Tag Archives: Amazon EMR

Amazon Web Services named a Leader in the 2024 Gartner Magic Quadrant for Data Integration Tools

Post Syndicated from William Vambenepe original https://aws.amazon.com/blogs/big-data/amazon-web-services-named-a-leader-in-the-2024-gartner-magic-quadrant-for-data-integration-tools/

Amazon Web Services (AWS) has been recognized as a Leader in the 2024 Gartner Magic Quadrant for Data Integration Tools. We were positioned in the Challengers Quadrant in 2023.

This recognition, we feel, reflects our ongoing commitment to innovation and excellence in data integration, demonstrating our continued progress in providing comprehensive data management solutions.

The Gartner Magic Quadrant evaluates 20 data integration tool vendors based on two axes—Ability to Execute and Completeness of Vision. This evaluation, we feel, critically examines vendors’ capabilities to address key service needs, including data engineering, operational data integration, modern data architecture delivery, and enabling less-technical data integration across various deployment models.

Discover, prepare, and integrate all your data at any scale

AWS Glue is a fully managed, serverless data integration service that simplifies data preparation and transformation across diverse data sources. With its comprehensive suite of tools, AWS Glue allows users to build and manage data pipelines efficiently, without requiring extensive infrastructure management expertise.

Given the diverse data integration needs of customers, AWS offers a robust data integration system through multiple services including Amazon EMR, Amazon Athena, Amazon Managed Workflows for Apache Airflow (Amazon MWAA), Amazon Managed Streaming for Apache Kafka (MSK), Amazon Kinesis, and others. Many thousands of customers across various industries are using these services to transform, operationalize, and manage their data across data lakes and data warehouses.

We have embarked on a journey to unify the broad range of AWS data processing, analytics, and AI capabilities, starting with the announcement of Amazon SageMaker Unified Studio at re:Invent 2024. This includes the data integration capabilities mentioned above, with support for both structured and unstructured data. With an integrated experience for data workers, SageMaker Unified Studio provides an environment where users can collaborate and build faster. It supports model development, generative AI, data processing, and SQL analytics, all accelerated by Amazon Q Developer—our most capable generative AI assistant for software development. The Unified Studio provides unified access to all data sources, whether stored in data lakes, data warehouses, or third-party and federated sources, with robust governance and enterprise-grade security built-in.

Review the Gartner Magic Quadrant

Access a complimentary copy of the full report to see why Gartner positioned AWS as a Leader, and dive deep into the strengths and cautions of AWS. We believe our recognition as a Leader in the Gartner Magic Quadrant is a testament to delivering innovations for our customers.

MQ

Gartner does not endorse any vendor, product or service depicted in its research publications and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner research publications consist of the opinions of Gartner’s research organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this research, including any warranties of merchantability or fitness for a particular purpose.

GARTNER is a registered trademark and service mark of Gartner and Magic Quadrant is a registered trademark of Gartner, Inc. and/or its affiliates in the U.S. and internationally and are used herein with permission. All rights reserved. This graphic was published by Gartner, Inc. as part of a larger research document and should be evaluated in the context of the entire document. The Gartner document is available upon request from here.


About the authors

William Vambenepe is Director of Product Management at AWS, where he leads the Product Management, Solutions Engineering, and UX Design team for data processing services (Amazon EMR, AWS Glue, Athena, Amazon MWAA), SageMaker Unified Studio, and SageMaker Catalog. Prior to AWS, William worked at Google (6 years building and growing the Data and Analytics product portfolio for Google Cloud, and 5 years as Product Management Director for Google Search). He had previously held software engineering leadership roles at Oracle and HP. William holds an Engineering degree from Ecole Centrale Paris, a graduate Diploma in Computer Science from Cambridge University, and a Masters in Engineering Management from Stanford University.

Santosh Chandrachood has been with AWS for over 8 years and helped build, launch, and scale a variety of AWS services. Currently, Santosh is Director and service leader for Data Processing, managing Amazon EMR, Athena, AWS Glue, and Managed Workflows for Apache Airflow (Amazon MWAA). Santosh also led AWS Data Integration as the General Manager. Before joining AWS, Santosh lead engineering teams in networking, storage, and data infrastructure areas.

Building and operating data pipelines at scale using CI/CD, Amazon MWAA and Apache Spark on Amazon EMR by Wipro

Post Syndicated from Senaka Ariyasinghe original https://aws.amazon.com/blogs/big-data/building-and-operating-data-pipelines-at-scale-using-ci-cd-amazon-mwaa-and-apache-spark-on-amazon-emr-by-wipro/

Businesses of all sizes are challenged with the complexities and constraints posed by traditional extract, transform and load (ETL) tools. These intricate solutions, while powerful, often come with a significant financial burden, particularly for small and medium enterprise customers. Beyond the substantial costs of procurement and licensing, customers must also contend with the expenses associated with installation, maintenance, and upgrades—a perpetual cycle of investment that can strain even the most robust budgets. At Wipro, scalability of data pipelines in addition to automation remains a persistent concern for their customers and they’ve learned through customer engagements that it’s not achievable without considerable effort. As data volumes continue to swell, these tools can struggle to keep pace with the ever-increasing demand, leading to processing delays and disruptions in data delivery—a critical bottleneck in an era when timely insights are paramount.

This blog post discusses how a programmatic data processing framework developed by Wipro can help data engineers overcome obstacles and streamline their organization’s ETL processes. The framework leverages Amazon EMR improved runtime for Apache Spark and integrates with AWS Managed services.  This framework is robust and capable of connecting with multiple data sources and targets. By using capabilities from AWS managed services, the framework eliminates the undifferentiated heavy lifting typically associated with infrastructure management in traditional ETL tools, enabling customers to allocate resources more strategically. Furthermore, we will show you how the framework’s inherent scalability ensures that businesses can effortlessly adapt to increasing data volumes, fostering agility and responsiveness in an evolving digital landscape.

Solution overview

The proposed solution helps build a fully automated data processing pipeline that streamlines the entire workflow. It triggers processes when code is pushed to Git, orchestrates and schedules processing of jobs, validates data with the help of defined rules, transforms data prescribed within code, and loads the transformed datasets into a specified target. The primary component of this solution is the robust framework, developed using Amazon EMR runtime for Apache Spark. The framework can be used for any ETL process where input might be fetched from various data sources, transformed, and loaded into specified targets. To enable gaining valuable insights and provide overall job monitoring and automation, the framework is integrated with AWS managed services:

Solution walkthrough

solution architecture

The solution architecture is shown in the preceding figure and includes:

  1. Continuous integration and delivery (CI/CD) for data processing
    • Data engineers can define the underlying data processing job within a JSON template. A pre-defined template is available on GitHub for you to review syntax. At a high level, this step includes the following objectives:
      • Writing the Spark job configuration to be executed on Amazon EMR.
      • Split the data processing into three phases:
        • Parallelize fetching data from source, validate source data, and prepare the dataset for further processing.
        • Provide flexibility to write business transformation rules defined in JSON, including data validation checks such as duplicate record, null value check, and their removal. It can also include any SQL based transformation written in Apache Spark SQL.
        • Take the transformed data set and load it to the target and perform reconciliation as needed.

It’s important to highlight that each step of the three phases is recorded for auditing, and error reporting, and troubleshooting and security purposes.

    • After the data engineer has prepared the configuration file following the prescribed template in step 1 and committed it to the Git repository, it triggers the Jenkins pipeline. Jenkins is an open source continuous integration tool running on an EC2 instance that takes the configuration file, processes it, and builds (compiles the Spark application code) end artifacts—a JAR file and a configuration file (.conf) that’s copied to an S3 bucket and will be used later by Amazon EMR.
  1. CI/CD for data pipeline

The CI/CD for the data pipeline is shown in the following figure.

CICD for the data pipeline

    • After the data processing job is written, the data engineers can use a similar code-driven development approach to define the data processing pipeline to schedule, orchestrate, and execute the data processing job. Apache Airflow is a popular open source platform used for developing, scheduling, and monitoring batch-oriented workflows. In this solution, we use Amazon MWAA to execute the data pipeline through a Direct Acyclic Graph (DAG). To make it easier for engineers to build the required DAG in this solution, you can define the data pipeline in simple YAML. A sample of the YAML file is available on GitHub for review.
    • When a user commits the YAML file containing the DAG details to the project Git repository, another Jenkins pipeline is triggered.
    • The Jenkins pipeline now reads the YAML configuration file and based on the task and dependencies given, it generates the DAG script file, which is copied to the configured S3 bucket.
  1. Airflow DAG execution
    • After both the data processing job and data pipeline are configured, Amazon MWAA retrieves the most recent scripts from the S3 bucket to display the latest DAG definition in the Airflow user interface. These DAGs contain at least three tasks and except for creating and terminating an EMR cluster, every task represents an ETL process. Sample DAG code is available in GitHub. The following figure shows the DAG grid view within Amazon MWAA.

    • As defined in the schedule specified in the job, Airflow executes the create Amazon EMR task that launches the Amazon EMR cluster on the EC2 instance. After the cluster is created, the ETL processes are submitted to Amazon EMR as steps.
    • Amazon EMR executes these steps concurrently (Amazon EMR provides step concurrency levels that define how many steps to process concurrently). After the tasks are finished, the Amazon EMR cluster is terminated to save costs.
  1. ETL processing
    • Each step submitted by Airflow to Amazon EMR with a Spark submit command also includes the S3 bucket path of the configuration file passed as an argument.
    • Based on the configuration file, the input data is fetched and technical validations are applied. If data mapping has been enabled within the data processing job, then the structured data is prepared based on the given schema. This output is passed to next phase where data transformations and business validations can be applied.
    • A set of reconciliation rules are applied to the transformed data to ensure the data quality dimensions. After this step, data is loaded to specified target.

The following figure shows the ETL data processing job as executed by Amazon EMR.

ETL data processing job

  1. Logging, monitoring and notification
    • Amazon MWAA provides the logs generated by each task of the DAG within the Airflow UI. Using these logs, you can monitor Apache Airflow task details, delays, and workflow errors.
    • Amazon MWAA also frequently pings the Amazon EMR cluster to fetch the latest status of the step being executed and updates the task status accordingly.
    • If a step has failed, for example, if the database connection was not established because of high traffic, Amazon MWAA repeats the process.
    • Whenever a task has failed, an email notification is sent to the configured recipients with the failure cause and logs using Amazon SNS.

The key capabilities of this solution are:

  • Full automation: After the user commits the configuration files to Git, the remainder of the process is fully automated from when the CI/CD pipelines deploy the artifacts and DAG code. The DAG code is later executed in Airflow at the scheduled time. The entire ETL job is logged and monitored, and email notifications are sent in case of any failures.
  • Flexible integration: The application can seamlessly accommodate a new ETL process with minimal effort. To create a new process, prepare a configuration file that contains the source and target details and the necessary transformation logic. An example of how to specify your data transformation is shown in the following sample code.
    "data_transformations": [{
    "functionName": "cast column date_processed",
    "sqlQuery": "Select *, from_unixtime(UNIX_TIMESTAMP(date_processed, 'yyyy-MM-dd HH:mm:ss'), 'dd/MM/yyyy') as dateprocessed from table_details",
    "outputDFName": "table_details"
    },
    {
    "functionName": "find the reference data from lookup",
    "sqlQuery": "join_query_table_lookup.sql",
    "outputDFName": "super_search_table_details"
    }]

  • Fault tolerance: In addition to Apache Spark’s fault-tolerant capabilities, this solution offers the ability to recover data even after the Amazon EMR has been terminated. The application solution has three phases. In the event of a failure in the Apache Spark job, the output of the last successful phase is temporarily stored in Amazon S3. When the job is triggered again through Airflow DAG, the Apache Spark job will resume from the point at which it previously failed, thereby ensuring continuity and minimizing disruptions to the workflow. The following figure shows job reporting in the Amazon MWAA UI.

job reporting in the Amazon MWAA UI.

  • Scalability: As shown in the following figure, the Amazon EMR cluster is configured to use instance fleet options to scale up or down the number of nodes depending on the size of the data, which makes this application an ideal choice for businesses with growing data needs.

instance fleet options to scale up or down

  • Customizable: This solution can be customized to meet the needs of specific use cases, allowing you to add your own transformations, validations, and reconciliations according to your unique data management requirements.
  • Enhanced data flexibility: By incorporating support for multiple file formats, the Apache Spark application and Airflow DAGs gain the ability to seamlessly integrate and process data from various sources. This advantage allows data engineers to work with a wide range of file formats, including JSON, XML, Text, CSV, Parquet, Avro, and so on.
  • Concurrent execution: Amazon MWAA submits the tasks to Amazon EMR for concurrent execution, using the scalability and performance of distributed computing to process large volumes of data efficiently.
  • Proactive error notification: Email notifications are sent to configured recipients whenever a task fails, providing timely awareness of failures and facilitating prompt troubleshooting.

Considerations

In our deployments, we have noticed that the average time of a DAG completion is 15–20 minutes containing 18 ETL processes concurrently and dealing with 900 thousand to 1.2 million records each. However, if you want to further optimize the DAG completion time, you can configure the core.dag_concurrency from the Amazon MWAA console as described in Example high performance use case.

Conclusion

The proposed code-driven data processing framework developed by Wipro using Amazon EMR Runtime for Apache Spark and Amazon MWAA demonstrates a solution to address the challenges associated with traditional ETL tools. By harnessing the capabilities from open source frameworks and seamlessly integrating with AWS services, you can build cost-effective, scalable, and automated approaches for your enterprise data processing pipelines.

Now that you have seen how to use Amazon EMR Runtime for Apache Spark with Amazon MWAA , we encourage you to use Amazon MWAA to create a workflow that will run your ETL jobs on Amazon EMR Runtime for Apache Spark.

The configuration file samples and example DAG code referred in this blog post can be found in GitHub.

References

Disclaimer

Sample code, software libraries, command line tools, proofs of concept, templates, or other related technology are provided as AWS Content or third-party content under the AWS Customer Agreement, or the relevant written agreement between you and AWS (whichever applies). You should not use this AWS Content or third-party content in your production accounts, or on production or other critical data. Performance metrics, including the stated DAG completion time, may vary based on the specific deployment environment. You are responsible for testing, securing, and optimizing the AWS Content or third-party content, such as sample code, as appropriate for production grade use based on your specific quality control practices and standards. Deploying AWS Content or Third-Party Content may incur AWS charges for creating or using AWS chargeable resources, such as running Amazon EC2 instances or using Amazon S3 storage.


About the Authors

Deependra Shekhawat is a Senior Energy and Utilities Industry Specialist Solutions Architect based in Sydney, Australia. In his role, Deependra helps Energy companies across APJ region use cloud technologies to drive sustainability and operational efficiency. He specializes in creating robust data foundations and advanced workflows that enable organizations to harness the power of big data, analytics, and machine learning for solving critical industry challenges.

Senaka Ariyasinghe is a Senior Partner Solutions Architect working with Global Systems Integrators at AWS. In his role, Senaka guides AWS partners in the APJ region to design and scale well-architected solutions, focusing on generative AI, machine learning, cloud migrations, and application modernization initiatives.

Sandeep Kushwaha is a Senior Data Scientist at Wipro and has extensive experience in big data and machine learning. With a strong command of Apache Spark, Sandeep has designed and implemented cutting-edge cloud solutions that optimize data processing and drive efficiency. His expertise in using AWS services and best practices, combined with his deep knowledge of data management and automation, has enabled him to lead successful projects that meet complex technical challenges and deliver high-impact results.

Enhance your workload resilience with new Amazon EMR instance fleet features

Post Syndicated from Deepmala Agarwal original https://aws.amazon.com/blogs/big-data/enhance-your-workload-resilience-with-new-amazon-emr-instance-fleet-features/

Big data processing and analytics have emerged as fundamental components of modern data architectures. Organizations worldwide use these capabilities to extract actionable insights and facilitate data-driven decision-making processes. Amazon EMR has long been a cornerstone for big data processing in the cloud. Now, with a suite of exciting new features for EMR instance fleets that enables you to effectively manage your compute, Amazon is taking cloud-based analytics to the next level.

Amazon EMR has introduced new features for instance fleets that address critical challenges in big data operations. This post explores how these innovations improve cluster resilience, scalability, and efficiency, enabling you to build more robust data processing architectures on AWS. This comprehensive post introduces instance fleets, demonstrates using this new allocation strategy, explores how enhanced Availability Zone and subnet selection works, and examines how these features improve cluster’s resilience. This technical exploration will equip you with the knowledge to implement more resilient and efficient EMR clusters for your organization’s big data processing needs.

The current challenges

Organizations using big data operations might face several challenges:

  • When preferred instance types are unavailable, finding suitable alternatives often delays cluster launches and disrupts workflows
  • Selecting the optimal Availability Zone for cluster launch is challenging due to constantly changing available compute capacity, especially when considering future scaling needs
  • Maintaining uninterrupted operation of mission-critical long-running clusters becomes complex as data processing requirements evolve over time
  • Organizations frequently struggle to scale their operations to meet growing data processing demands, leading to performance bottlenecks and delayed insights

These challenges underscore the need for more advanced, flexible, and intelligent solutions in the realm of big data operations, driving the demand for innovative features in cloud-based data processing platforms.

Introducing improved EMR instance fleets

Amazon EMR, a cloud-based big data platform, allows you to process large datasets using various open source tools such as Apache Spark, Apache Flink, and Trino. To address the aforementioned challenges, Amazon EMR introduced instance fleets, with a robust set of features.

When setting up an EMR cluster, Amazon EMR offers two configuration options for configuring the primary, core, and task nodes: uniform instance groups or instance fleets.

Uniform instance groups offer a streamlined approach to cluster setup, allowing up to 50 instance groups per cluster. An EMR cluster has a primary instance group for primary node, a core instance group with one or more Amazon Elastic Compute Cloud (Amazon EC2) instances, and the option to add up to 48 task instance groups. Both core and task instance groups are flexible, allowing any number of EC2 instances within each group. Both core and task groups offer flexibility in instance count, and each node type (primary, core, or task) consists of instances sharing the same specifications and purchasing model (On-Demand or Spot). However, this approach limits the ability to mix different instance types or purchasing options within a single group.

Instance fleets provide a versatile approach to provisioning EC2 instances, offering unparalleled flexibility in cluster configuration. This setup assigns one instance fleet each for primary and core nodes, with the task instance fleet being optional. It allows you to specify up to five EC2 instance types (or up to 30 when using the Amazon Command Line Interface (AWS CLI) or API with an instance allocation strategy) for each node type in a cluster, providing enhanced instance diversity to optimize cost and performance while increasing the likelihood of fulfilling capacity requirements. Instance fleets automatically manage the mix of instance types to meet specified target capacities for On-Demand and Spot, reducing operational overhead and improving compute availability.

Key benefits of instance fleets include improved cluster resilience to capacity fluctuations, superior management of Spot Instances with the ability to set timeouts and specify actions if Spot capacity can’t be provisioned, and faster cluster provisioning. The feature also allows you to select multiple subnets for different Availability Zones, enabling Amazon EMR to optimally launch clusters and automatically route traffic away from impacted zones during large-scale events. Additionally, instance fleets offer capacity reservation options for On-Demand Instances and support allocation strategies that prioritize instance types based on user-defined criteria, further enhancing the flexibility and efficiency of EMR cluster management.

Achieve resiliency with instance fleets

Now that you have a good understanding of instance fleets, let’s explore how the new instance fleet capabilities help achieve resiliency for your workloads through the following methods:

  • EC2 instance allocation – Enables precise control over instance type selection and prioritization
  • Enhanced subnet selection – Optimizes cluster deployment across Availability Zones

EC2 instance allocation

EMR instance fleets now offer newer allocation strategies for both Spot and On-Demand Instances, giving you control over selection and prioritization of instance types and allowing you to optimize for greater flexibility, resilience, and cost-efficiency.

Amazon EMR supports the following allocation strategies for On-Demand Instances:

  • Prioritized (new) – Allows you to define a priority order for instance types, giving you precise control over instance selection
  • Lowest-price (existing) – Selects the lowest-priced instance type from the available options

Amazon EMR supports the following allocation strategies for Spot Instances:

  • Price-capacity optimized (new) – Selects instances with the lowest price while also considering the available capacity
  • Capacity-optimized-prioritized (new) – Similar to capacity-optimized, but respects instance type priorities that you specify, on a best-effort basis
  • Capacity-optimized (existing) – Selects instances from the pools with the most available capacity
  • Lowest-price (existing) – Selects the lowest-priced Spot Instances
  • Diversified (existing) – Distributes instances across all pools

When using the prioritized On-Demand allocation strategy, Amazon EMR applies the same priority value to both your On-Demand and Spot Instances when you set priorities.

For Spot Instances, Amazon EMR recommends the capacity-optimized allocation strategy. This approach allocates instances from the most available capacity pools, thereby reducing the chance of interruptions and enhancing cluster stability. Amazon EMR also allows you to launch a cluster without an allocation strategy. However, using an allocation strategy is recommended for faster cluster provisioning, more accurate Spot Instance allocation, and fewer Spot Instance interruptions.

Enhanced subnet selection

Amazon EMR on EC2 offers improved reliability and cluster launch experience for instance fleet clusters through the newly launched enhanced subnet selection. With this feature, EMR on EC2 reduces cluster launch failures resulting from an IP address shortage. Previously, the subnet selection for EMR clusters only considered the available IP addresses for the core instance fleet. Amazon EMR now employs subnet filtering at cluster launch and selects one of the subnets that have adequate available IP addresses to successfully launch all instance fleets. If Amazon EMR can’t find a subnet with sufficient IP addresses to launch the whole cluster, it will prioritize the subnet that can at least launch the core and primary instance fleets. In this scenario, Amazon EMR will also publish an Amazon CloudWatch alert event to notify the user. If none of the configured subnets can be used to provision the core and primary fleet, Amazon EMR will fail the cluster launch and provide a critical error event. These CloudWatch events enable you to monitor your clusters and take remedial actions as necessary. This capability is enabled by default when you configure more than one subnet for cluster launch, and you don’t need to make any configuration changes to benefit from it.

Solution overview

Now that you have a comprehensive grasp of the two new features, let’s integrate the elements of instance fleets and look at the implementation flow for each feature.

EC2 instance allocation

The following diagram illustrates the instance fleet lifecycle management architecture.

The workflow consists of the following steps:

  1. Create a cluster configuration with the prioritized allocation strategy, specifying instance types, their priority, and a list of potential subnets.
  2. When you launch an EMR cluster, it evaluates compute capacity and available IPs across the specified subnets. Amazon EMR then selects a single Availability Zone that best meets capacity and instance availability needs for the entire cluster.
  3. Amazon EMR launches the cluster using available instance types in one of the configured Availability Zones based on enhanced subnet selection.
  4. During a scale-up scenario, Amazon EMR adds new instances to the clusters while following the configured compute allocation strategy.
  5. If a specific instance type is unavailable, Amazon EMR will select the next available instance types based on the priority order. This flexibility provides capacity availability for production workloads while maintaining scalability.

The following example code provisions an EMR cluster with a primary and core instance fleet configuration with both Spot and On-Demand Instances, using the Capacity-optimized-prioritized allocation strategy for Spot Instances and the Prioritized strategy for On-Demand Instances:

{
  "AWSTemplateFormatVersion": "2010-09-09",
  "Resources": {
    "myCluster": {
      "Type": "AWS::EMR::Cluster",
      "Properties": {
        "Instances": {
          "MasterInstanceFleet": {
            "Name": "cfnPrimary",
            "InstanceTypeConfigs": [
              {
                "BidPrice": "10.50",
                "InstanceType": "m5.xlarge",
                "Priority": "1",
                "EbsConfiguration": {
                  "EbsBlockDeviceConfigs": [
                    {
                      "VolumeSpecification": {
                        "VolumeType": "gp2",
                        "SizeInGB": 32
                      }
                    }
                  ]
                }
              }
            ],
            "TargetOnDemandCapacity": 1
          },
          "CoreInstanceFleet": {
            "Name": "cfnCore",
            "InstanceTypeConfigs": [
              {
                "BidPrice": "10.50",
                "InstanceType": "m5.xlarge",
                "Priority": "1",
                "WeightedCapacity": "1",
                "EbsConfiguration": {
                  "EbsBlockDeviceConfigs": [
                    {
                      "VolumeSpecification": {
                        "VolumeType": "gp2",
                        "SizeInGB": 32
                      }
                    }
                  ]
                }
              }
            ],
            "LaunchSpecifications": {
              "SpotSpecification": {
                "TimeoutAction": "SWITCH_TO_ON_DEMAND",
                "TimeoutDurationMinutes": 20,
                "AllocationStrategy": "CAPACITY_OPTIMIZED_PRIORITIZED"
              },
              "OnDemandSpecification": {
                "AllocationStrategy": "PRIORITIZED"
              }
            },
            "TargetOnDemandCapacity": "5",
            "TargetSpotCapacity": "0"
          }
        },
        "Name": "blog-test",
        "JobFlowRole": "EMR_EC2_DefaultRole",
        "ServiceRole": "EMR_DefaultRole",
        "ReleaseLabel": "emr-7.2.0"
      }
    }
  }
}

Enhanced subnet selection

To better understand Step 3 in the preceding workflow, let’s explore how enhanced subnet selection works with instance fleet EMR clusters.

For our example, let’s configure an EMR instance fleet as follows:

  • Primary fleet (1 unit) – r8g.xlarge, r6g.xlarge, r8g.2xlarge
  • Core fleet (48 units) – r6g.xlarge, r6g.2xlarge, m7g.2xlarge
  • Task fleet (48 units) – m7g.2xlarge, r6g.xlarge, r6a.4xlarge

For this example, let’s use the lowest price allocation strategy. Next, let’s check the available IP addresses in our subnets using the AWS CLI:

aws ec2 describe-subnets 
--query "sort_by(Subnets, &SubnetId)[*].[SubnetId, AvailableIpAddressCount, AvailabilityZoneId]" 
--output table

We get the following results:

--------------------------------------------------
|                 DescribeSubnets                |
+---------------------------+-------+------------+
|subnet-XXXXXXXXXXXXXXXX1   |  27  |  us-east-1a |
|subnet-XXXXXXXXXXXXXXXX2   |  251 |  us-east-1b |
|subnet-XXXXXXXXXXXXXXXX3   |  11  |  us-east-1a |
-------------------------------------------------

When launching an EMR cluster, Amazon EMR follows a specific subnet filtering process. First, EMR on EC2 evaluates subnets based on the total IP addresses required for all node types: primary, core, and task nodes. If multiple subnets have sufficient IP capacity to accommodate all instance fleets, Amazon EMR selects one based on the cluster’s allocation strategy. However, if no subnet has enough IPs to support all node types, Amazon EMR considers subnets that can at least accommodate the primary and core nodes, again using the allocation strategy to make the final selection. In our case, Amazon EMR selected a subnet in Availability Zone us-east-1b that had 251 available IPs that can support 97 instances to launch the whole cluster, bypassing smaller subnets with only 27 or 11 available IPs because they didn’t meet the minimum IP requirements for the cluster configuration.

  • Primary fleet (1 unit) – r6g.xlarge
  • Core fleet (48 units) – m7g.2xlarge
  • Task fleet (48 units) – r6g.xlarge

The EMR and CloudWatch event for this cluster would be:

Amazon EMR cluster j-X40BEI1Oxxx (Cluster) 
is being created in subnet (subnet-XXXXXXXXXXXXXXXX2) 
in VPC (vpc-XXXXXXXXXXXXXXXX1) in Availability Zone (us-east-1b), 
which was chosen from the specified VPC options.

If Amazon EMR can’t find a subnet with sufficient IP addresses to launch the entire cluster, it will prioritize launching the core and primary instance fleets. If no configured subnet can accommodate even the core and primary fleets, Amazon EMR will fail the cluster launch and provide a critical error event. These CloudWatch events enable you to monitor your clusters and take necessary actions.

Conclusion

The latest enhancements to EMR instance fleets mark a significant advancement in cloud-based big data processing, addressing key challenges in resource allocation, scalability, and reliability. These features, including priority-based instance selection and enhanced subnet selection, provide you with greater control over resource strategies, improved cluster availability, enhanced capacity optimization across Availability Zones, and more efficient fallback mechanisms for production workloads. Instance fleets help you tackle current resource management challenges while laying the groundwork for future scalability.

Get started today by setting up an EMR cluster using the example configuration provided in this post. For additional configuration options and implementation guidance, refer here or reach out to your AWS account team.


About the Authors

Deepmala Agarwal works as an AWS Data Specialist Solutions Architect. She is passionate about helping customers build out scalable, distributed, and data-driven solutions on AWS. When not at work, Deepmala likes spending time with family, walking, listening to music, watching movies, and cooking!

Ravi Kumar Singh is a Senior Product Manager Technical-ES (PMT) at Amazon Web Services, specialized in building petabyte-scale data infrastructure and analytics platforms. With a passion for building innovative tools, he helps customers unlock valuable insights from their structured and unstructured data. Ravi’s expertise lies in creating robust data foundations using open source technologies and advanced cloud computing that power advanced artificial intelligence and machine learning use cases. A recognized thought leader in the field, he advances the data and AI ecosystem through pioneering solutions and collaborative industry initiatives. As a strong advocate for customer-centric solutions, Ravi constantly seeks ways to simplify complex data challenges and enhance user experiences. Outside of work, Ravi is an avid technology enthusiast who enjoys exploring emerging trends in data science, cloud computing, and machine learning.

Mandisa Nxumalo is a Cloud Engineer at Amazon Web Services (AWS) with over 5 years experience in topics related to cloud services (databases, automation, and others). Currently, specializing in Big data service Amazon EMR. She is passionate about engaging customers to effectively adopt and utilize data driven approaches to improve their big data workflows. Outside work, Mandisa enjoys hiking mountains, chasing waterfalls and travelling across countries.

Kashif Khan is a Sr. Analytics Specialist Solutions Architect at AWS, specializing in big data services like Amazon EMR, AWS Lake Formation, AWS Glue, Amazon Athena, and Amazon DataZone. With over a decade of experience in the big data domain, he possesses extensive expertise in architecting scalable and robust solutions. His role involves providing architectural guidance and collaborating closely with customers to design tailored solutions using AWS analytics services to unlock the full potential of their data.

Gaurav Sharma is a Specialist Solutions Architect (Analytics) at AWS, supporting US public sector customers on their cloud journey. Outside of work, Gaurav enjoys spending time with his family and reading books.

Hybrid big data analytics with Amazon EMR on AWS Outposts

Post Syndicated from Shoukat Ghouse original https://aws.amazon.com/blogs/big-data/hybrid-big-data-analytics-with-amazon-emr-on-aws-outposts/

Businesses require powerful and flexible tools to manage and analyze vast amounts of information. Amazon EMR has long been the leading solution for processing big data in the cloud. Amazon EMR is the industry-leading big data solution for petabyte-scale data processing, interactive analytics, and machine learning using over 20 open source frameworks such as Apache Hadoop, Hive, and Apache Spark. However, data residency requirements, latency issues, and hybrid architecture needs often challenge purely cloud-based solutions.

Enter Amazon EMR on AWS Outposts—a groundbreaking extension that brings the power of Amazon EMR directly to your on-premises environments. This innovative service merges the scalability, performance (the Amazon EMR runtime for Apache Spark is 4.5 times more performant than Apache Spark 3.5.1), and ease of Amazon EMR with the control and proximity of your data center, empowering enterprises to meet stringent regulatory and operational requirements while unlocking new data processing possibilities.

In this post, we dive into the transformative features of EMR on Outposts, showcasing its flexibility as a native hybrid data analytics service that allows seamless data access and processing both on premises and in the cloud. We also explore how it integrates smoothly with your existing IT infrastructure, providing the flexibility to keep your data where it best fits your needs while performing computations entirely on premises. We examine a hybrid setup where sensitive data remains locally in Amazon S3 on Outposts and public data in an AWS Regional Amazon Simple Storage Service bucket. This configuration allows you to augment your sensitive on-premises data with cloud data while making sure all data processing and compute runs on-premises in AWS Outposts Racks.

Solution overview

Consider a fictional company named Oktank Finance. Oktank aims to build a centralized data lake to store vast amounts of structured and unstructured data, enabling unified access and supporting advanced analytics and big data processing for data-driven insights and innovation. Additionally, Oktank must comply with data residency requirements, making sure that confidential data is stored and processed strictly on premises. Oktank also needs to enrich their datasets with non-confidential and public market data stored in the cloud on Amazon S3, which means they should be able to join datasets across their on-premises and cloud data stores.

Traditionally, Oktank’s big data platforms tightly coupled compute and storage resources, creating an inflexible system where decommissioning compute nodes could lead to data loss. To avoid this situation, Oktank aims to decouple compute from storage, allowing them to scale down compute nodes and repurpose them for other workloads without compromising data integrity and accessibility.

To meet these requirements, Oktank decides to adopt Amazon EMR on Outposts as their big data analytics platform and Amazon S3 on Outposts as their on-premises data store for their data lake. With EMR on Outposts, Oktank can make sure that all compute occurs on premises within their Outposts rack while still being able to query and join the public data stored in Amazon S3 with their confidential data stored in S3 on Outposts, using the same unified data APIs. For data processing, Oktank can choose from a wide variety of applications available on Amazon EMR. In this post, we use Spark as the data processing framework.

This approach makes sure that all data processing and analytics are performed locally within their on-premises environment, allowing Oktank to maintain compliance with data privacy and regulatory requirements. Simultaneously, by avoiding the need to replicate public data to their on-premises data centers, Oktank reduces storage costs and simplifies their end-to-end data pipelines by eliminating additional data movement jobs.

The following diagram illustrates the high-level solution architecture.

As explained earlier, the S3 on Outposts bucket in the architecture holds Oktank’s sensitive data, which stays on the Outpost in Oktank’s data center while the Regional S3 bucket holds the non-sensitive data.

In this post, to achieve high network performance from the Outpost to the Regional S3 bucket and vice-versa, we also use AWS Direct Connect with a virtual private gateway. This is especially beneficial when you need higher query throughput to the Regional S3 bucket by making sure the traffic is routed through your own dedicated network channel to AWS.

The solution involves deploying an EMR cluster on an Outposts rack. A service link connects AWS Outposts to a Region. The service link is a necessary connection between your Outposts and the Region (or home Region). It allows for the management of the Outposts and the exchange of traffic to and from the Region.

You can also access Regional S3 buckets using this service link. However, in this post, we employ an alternate option to enable the EMR cluster to privately access the Regional S3 bucket through the local gateway. This helps optimize data access from the Regional S3 bucket as traffic is routed through Direct Connect.

To enable the EMR cluster to access Amazon S3 privately over Direct Connect, a route is configured in the Outposts subnet (marked as 2 in the architecture diagram) to direct Amazon S3 traffic through the local gateway. Upon reaching the local gateway, the traffic is routed over Direct Connect (private virtual interface) to a virtual private gateway in the Region. The second VPC (5 in diagram), which includes the S3 interface endpoint, is connected to this virtual private gateway. A route is then added to make sure that traffic can return to the EMR cluster. This setup provides more efficient, higher-bandwidth communication between the EMR cluster and Regional S3 buckets.

For big data processing, we use Amazon EMR. Amazon EMR supports access to local S3 on Outposts with the Apache Hadoop S3A connector from Amazon EMR version 7.0.0 onwards. EMR File System (EMRFS) with S3 on Outposts is not supported. We use EMR Studio notebooks for running interactive queries on the data. We also submit Spark jobs as a step on the EMR cluster. We also use the AWS Glue Data Catalog as the external Hive compatible metastore, which serves as the central technical metadata catalog. The Data Catalog is a centralized metadata repository for all your data assets across various data sources. It provides a unified interface to store and query information about data formats, schemas, and sources. Additionally, we use AWS Lake Formation for access controls on the AWS Glue table. You still need to control the raw files access on the S3 on Outposts bucket with AWS Identity and Access Management (IAM) permissions in this architecture. At the time of writing, Lake Formation can’t directly manage access to data on the S3 on Outposts bucket. Access to the actual data files stored in the S3 on Outposts bucket is managed with IAM permissions.

In the following sections, you will implement this architecture for Oktank. We focus on a specific use case for Oktank Finance, where they maintain sensitive customer stockholding data in a local S3 on Outposts bucket. Additionally, they have publicly available stock details stored in a Regional S3 bucket. Their goal is to explore both the datasets within their on-premises Outpost setup. Additionally, they need to enrich the customer stock holdings data by combining it with the publicly available stock details data.

First, we explore how to access both datasets using an EMR cluster. Then, we demonstrate the process of performing joins between the local and public data. We also demonstrate how to use Lake Formation to effectively manage permissions for these tables. We explore two primary scenarios throughout this walkthrough. In the interactive use case, we demonstrate how users can connect to the EMR cluster and run queries interactively using EMR Studio notebooks. This approach allows for real-time data exploration and analysis. Additionally, we show you how to submit batch jobs to Amazon EMR using EMR steps for automated, scheduled data processing. This method is ideal for recurring tasks or large-scale data transformations.

Prerequisites

Complete the following prerequisite steps:

  1. Have an AWS account and a role with administrator access. If you don’t have an account, you can create one.
  2. Have an Outposts rack installed and running.
  3. Create an EC2 key pair. This allows you to connect to the EMR cluster nodes even if Regional connectivity is lost.
  4. Set up Direct Connect. This is required only if you want to deploy the second AWS CloudFormation template as explained in the following section.

Deploy the CloudFormation stacks

In this post, we’ve divided the setup into four CloudFormation templates, each responsible for provisioning a specific component of the architecture. The templates come with default parameters, which you may need to adjust based on your specific configuration requirements.

Stack1 provisions the network infrastructure on Outposts. It also creates the S3 on Outposts bucket and Regional S3 bucket. It copies the sample data to the buckets to simulate the data setup for Oktank. Confidential data for customer stock holdings is copied to the S3 on Outposts bucket, and non-confidential data for stock details is copied to the Regional S3 bucket.

Stack2 provisions the infrastructure to connect to the Regional S3 bucket privately using Direct Connect. It establishes a VPC with private connectivity to both the regional S3 bucket and the Outposts subnet. It also creates an Amazon S3 VPC interface endpoint to allow private access to Amazon S3. It establishes a virtual private gateway for connectivity between the VPC and Outposts subnet. Lastly, it configures a private Amazon Route 53 hosted zone for Amazon S3, enabling private DNS resolution for S3 endpoints within the VPC. You can skip deploying this stack if you don’t need to route traffic using Direct Connect.

Stack3 provisions the EMR cluster infrastructure, AWS Glue database, and AWS Glue tables. The stack creates an AWS Glue database named oktank_outpostblog_temp and three tables under it: stock_details, stockholdings_info, and stockholdings_info_detailed. The table stock_details contains public information for the stocks, and the data location of this table points to the Regional S3 bucket. The tables stockholdings_info and stockholdings_info_detailed contain confidential information, and their data location is in the S3 on Outposts bucket. It also creates a runtime role named outpostblog-runtimeRole1. A runtime role is an IAM role that you associate with an EMR step, and jobs use this role to access AWS resources. With runtime roles for EMR steps, you can specify different IAM roles for the Spark and the Hive jobs, thereby scoping down access at a job level. This allows you to simplify access controls on a single EMR cluster that is shared between multiple tenants, wherein each tenant can be isolated using IAM roles. This stack also grants the required permissions on the runtime role to grant access on the Regional S3 bucket and the S3 on Outposts bucket. The EMR cluster uses a bootstrap action that runs a script to copy sample data to the S3 on Outposts bucket and the Regional S3 bucket for the two tables.

Stack4 provisions the EMR Studio. We will connect to EMR Studio notebook and interact with the data stored across S3 on Outposts and the Regional S3 bucket. This stack outputs the EMR Studio URL, which you can use to connect to EMR Studio.

Run the preceding CloudFormation stacks in sequence with an admin role to create the solution resources.

Access the data and join tables

To verify the solution, complete the following steps:

  1. On the AWS CloudFormation console, navigate to the Outputs tab of Stack4, which deployed the EMR Studio, and choose the EMR Studio URL.

This will open EMR Studio in a new window.

  1. Create a workspace and use the default options.

The workspace will launch in a new tab.

  1. Connect to the EMR cluster using the runtime role (outpostblog-runtimeRole1).

You are now connected to the EMR cluster.

  1. Choose the File Browser tab and open the notebook while choosing the kernel as PySpark.
    File browser tab
  2. Run the following query in the notebook to read from the stock details table. This table points to public data stored in the Regional S3 bucket.
    spark.sql("select * from oktank_outpostblog_temp.stock_details").show(5)

    Public data stored

  3. Run the following query to read from the confidential data stored in the local S3 on Outposts bucket:
    spark.sql("select * from oktank_outpostblog_temp.stockholdings_info").show(5)

    Confidential data

As highlighted earlier, one of the requirements for Oktank is to enrich the preceding data with data from the Regional S3 bucket.

  1. Run the following query to join the preceding two tables:
    spark.sql("select customerid,sharesheld,purchasedate, a.stockid, b.stockname,b.category,b.currentprice from oktank_outpostblog_temp.stockholdings_info a inner join oktank_outpostblog_temp.stock_details b on a.stockid=b.stockid order by customerid").show(10)

    S3 on Outposts

Control access to tables using Lake Formation

In this post, we also showcase how you can control access to the tables using Lake Formation. To demonstrate, let’s block access to RuntimeRole1 on the stockholdings_info table.

  1. On the Lake Formation console, choose Tables in the navigation pane.
  2. Select the table stockholdings_info and on the Actions menu, choose View to view the current access permissions on this table.
    AWS Lake Formation
  3. Select IAMAllowedPrincipals from the list of principals and choose Revoke to revoke the permission.
    Revoke permissions
  4. Go back to the EMR Studio notebook and rerun the earlier query.
    Data access query fails

Oktank’s data access query fails because Lake Formation has denied permission to the runtime role; you will need to adjust the permissions.

  1. To resolve this issue, return to the Lake Formation console, select the stockholdings_info table, and on the Actions menu, choose Grant.
  2. Assign the necessary permissions to the runtime role to make sure it can access the table.
    Grant permission
  3. Select IAM users and roles and choose the runtime role (outpostblog-runtimeRole1).
    Grant data lake permissions
  4. Choose the table stockholdings_info from the list of tables and for Table permissions, select Select.
    Table permissions
  5. Select All data access and choose Grant.
    Data permissions
  6. Go back to the notebook and rerun the query.
    Rerun the query

The query now succeeds because we granted access to the runtime role connected to the EMR cluster through the EMR Studio notebook. This demonstrates how Lake Formation allows you to manage permissions on your Data Catalog tables.

The previous steps only restrict access to the table in the catalog, not to the actual data files stored in the S3 on Outposts bucket. To control access to these data files, you need to use IAM permissions. As mentioned earlier, Stack3 in this post handles the IAM permissions for the data. For access control on the Regional S3 bucket with Lake Formation, you don’t need to specifically provide IAM permissions on the specific S3 bucket to the roles. Lake Formation manages the Regional S3 bucket access controls for runtime roles. Refer to Introducing runtime roles for Amazon EMR steps: Use IAM roles and AWS Lake Formation for access control with Amazon EMR for detailed guidance on managing access to a Regional S3 bucket with Lake Formation and EMR runtime roles.

Submit a batch job

Next, let’s submit a batch job as an EMR step on the EMR cluster. Before we do that, let’s confirm there is currently no data in the table stockholdings_info_detailed. Run the following query in the notebook:

spark.sql("select * from oktank_outpostblog_temp.stockholdings_info_detailed").show(10)

Submit a batch job
You will not see any data in this table. You can now detach the notebook from the cluster.
You will now insert data in this table using a batch job submitted as an EMR step.

  1. On the EMR console, navigate to the cluster EMROutpostBlog and submit a step.
  2. Choose Spark Application for Type.
  3. Select the py script from the scripts folder in your S3 bucket created by the CloudFormation template.
  4. For Permissions, choose the runtime role (outpostblog-RuntimeRole1).
  5. Choose Add step to submit the job.

Wait for the job to complete. The job inserted data into the stockholdings_info_detailed table. You can rerun the earlier query in the notebook to verify the data:

spark.sql("select * from oktank_outpostblog_temp.stockholdings_info_detailed").show(10)

Verify the data

Clean up

To avoid incurring further charges, delete the CloudFormation stacks.

  1. Before deleting Stack4, run the following shell command (with the %%sh magic command) in the EMR Studio notebook to delete the objects from the S3 on Outposts bucket:
    aws s3api delete-objects --bucket <replace with value of key S3OutpostBucketAccessPointAlias1 from stack 3 output> --delete "$(aws s3api list-object-versions --bucket <replace with value of key S3OutpostBucketAccessPointAlias1 from stack 3 output> --output=json | jq '{Objects: [.Versions[]|{Key:.Key,VersionId:.VersionId}], Quiet: true}')"

    Delete the objects from the S3 on Outposts bucket

  2. Next, manually delete the EMR workspace from the EMR Studio.
  3. You can now delete the stacks, starting with Stack4, Stack3, Stack2, and finally Stack1.

Conclusion

In this post, we demonstrated how to use Amazon EMR on Outposts as a managed big data processing service in your on-premises setup. We explored how you can set up the cluster to access data stored in an S3 on Outposts bucket on premises and also efficiently access data in the Regional S3 bucket with private networking. We also explored Glue Data Catalog as a serverless external Hive metastore and managed access control to the catalog tables using Lake Formation. We accessed the data interactively using EMR Studio notebooks and processed it as a batch job using EMR steps.

To learn more, visit Amazon EMR on AWS Outposts.

For further reading, refer to the following resources:


About the Authors

Shoukat Ghouse is a Senior Big Data Specialist Solutions Architect at AWS. He helps customers around the world build robust, efficient and scalable data platforms on AWS leveraging AWS analytics services like AWS Glue, AWS Lake Formation, Amazon Athena and Amazon EMR.

Fernando Galves is an Outpost Solutions Architect at AWS, specializing in networking, security, and hybrid cloud architectures. He helps customers design and implement secure hybrid environments using AWS Outposts, focusing on complex networking solutions and seamless integration between on-premises and cloud infrastructure.

Amazon EMR 7.5 runtime for Apache Spark and Iceberg can run Spark workloads 3.6 times faster than Spark 3.5.3 and Iceberg 1.6.1

Post Syndicated from Atul Payapilly original https://aws.amazon.com/blogs/big-data/amazon-emr-7-5-runtime-for-apache-spark-and-iceberg-can-run-spark-workloads-3-6-times-faster-than-spark-3-5-3-and-iceberg-1-6-1/

The Amazon EMR runtime for Apache Spark offers a high-performance runtime environment while maintaining 100% API compatibility with open source Apache Spark and Apache Iceberg table format. Amazon EMR on EC2, Amazon EMR Serverless, Amazon EMR on Amazon EKS, Amazon EMR on AWS Outposts and AWS Glue all use the optimized runtimes.

In this post, we demonstrate the performance benefits of using the Amazon EMR 7.5 runtime for Spark and Iceberg compared to open source Spark 3.5.3 with Iceberg 1.6.1 tables on the TPC-DS 3TB benchmark v2.13.

Iceberg is a popular open source high-performance format for large analytic tables. Our benchmarks demonstrate that Amazon EMR can run TPC-DS 3 TB workloads 3.6 times faster, reducing the runtime from 1.54 hours to 0.42 hours. Additionally, the cost efficiency improves by 2.9 times, with the total cost decreasing from $16.00 to $5.39 when using Amazon Elastic Compute Cloud (Amazon EC2) On-Demand r5d.4xlarge instances, providing observable gains for data processing tasks.

This is a further 32% increase from the optimizations shipped in Amazon EMR 7.1 covered in a previous post, Amazon EMR 7.1 runtime for Apache Spark and Iceberg can run Spark workloads 2.7 times faster than Apache Spark 3.5.1 and Iceberg 1.5.2. Since then we have continued adding more support for DataSource V2 for eight more existing query optimizations in the EMR runtime for Spark.

In addition to these DataSource V2 specific improvements, we have made more optimizations to Spark operators since Amazon EMR 7.1 that also contribute to the additional speedup.

Benchmark results for Amazon EMR 7.5 compared to4 open source Spark 3.5.3 and Iceberg 1.6.1

To assess the Spark engine’s performance with the Iceberg table format, we performed benchmark tests using the 3 TB TPC-DS dataset, version 2.13 (our results derived from the TPC-DS dataset are not directly comparable to the official TPC-DS results due to setup differences). Benchmark tests for the EMR runtime for Spark and Iceberg were conducted on Amazon EMR 7.5 EC2 clusters vs open source Spark 3.5.3 and Iceberg 1.6.1 on EC2 clusters.

The setup instructions and technical details are available in our GitHub repository. To minimize the influence of external catalogs like AWS Glue and Hive, we used the Hadoop catalog for the Iceberg tables. This uses the underlying file system, specifically Amazon S3, as the catalog. We can define this setup by configuring the property spark.sql.catalog.<catalog_name>.type. The fact tables used the default partitioning by the date column, which have a number of partitions varying from 200–2,100. No precalculated statistics were used for these tables.

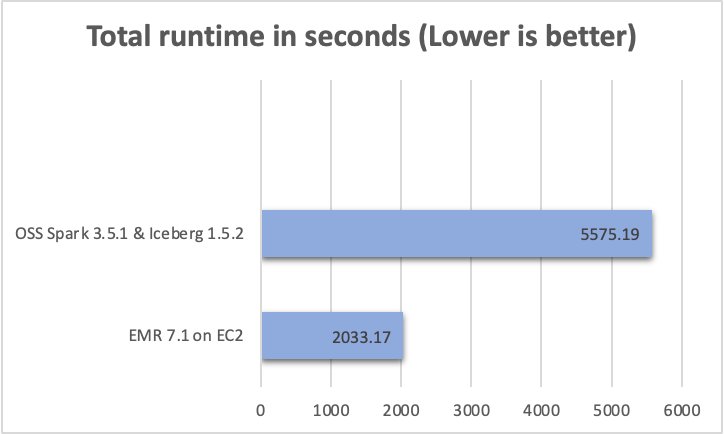
We ran a total of 104 SparkSQL queries in three sequential rounds, and the average runtime of each query across these rounds was taken for comparison. The average runtime for the three rounds on Amazon EMR 7.5 with Iceberg enabled was 0.42 hours, demonstrating a 3.6-fold speed increase compared to open source Spark 3.5.3 and Iceberg 1.6.1. The following figure presents the total runtimes in seconds.

EMR vs OSS runtime

The following table summarizes the metrics.

Metric Amazon EMR 7.5 on EC2 Amazon EMR 7.1 on EC2 Open Source Spark 3.5.3 and Iceberg 1.6.1
Average runtime in seconds 1535.62 2033.17 5546.16
Geometric mean over queries in seconds 8.30046 10.13153 20.40555
Cost* $5.39 $7.18 $16.00

*Detailed cost estimates are discussed later in this post.

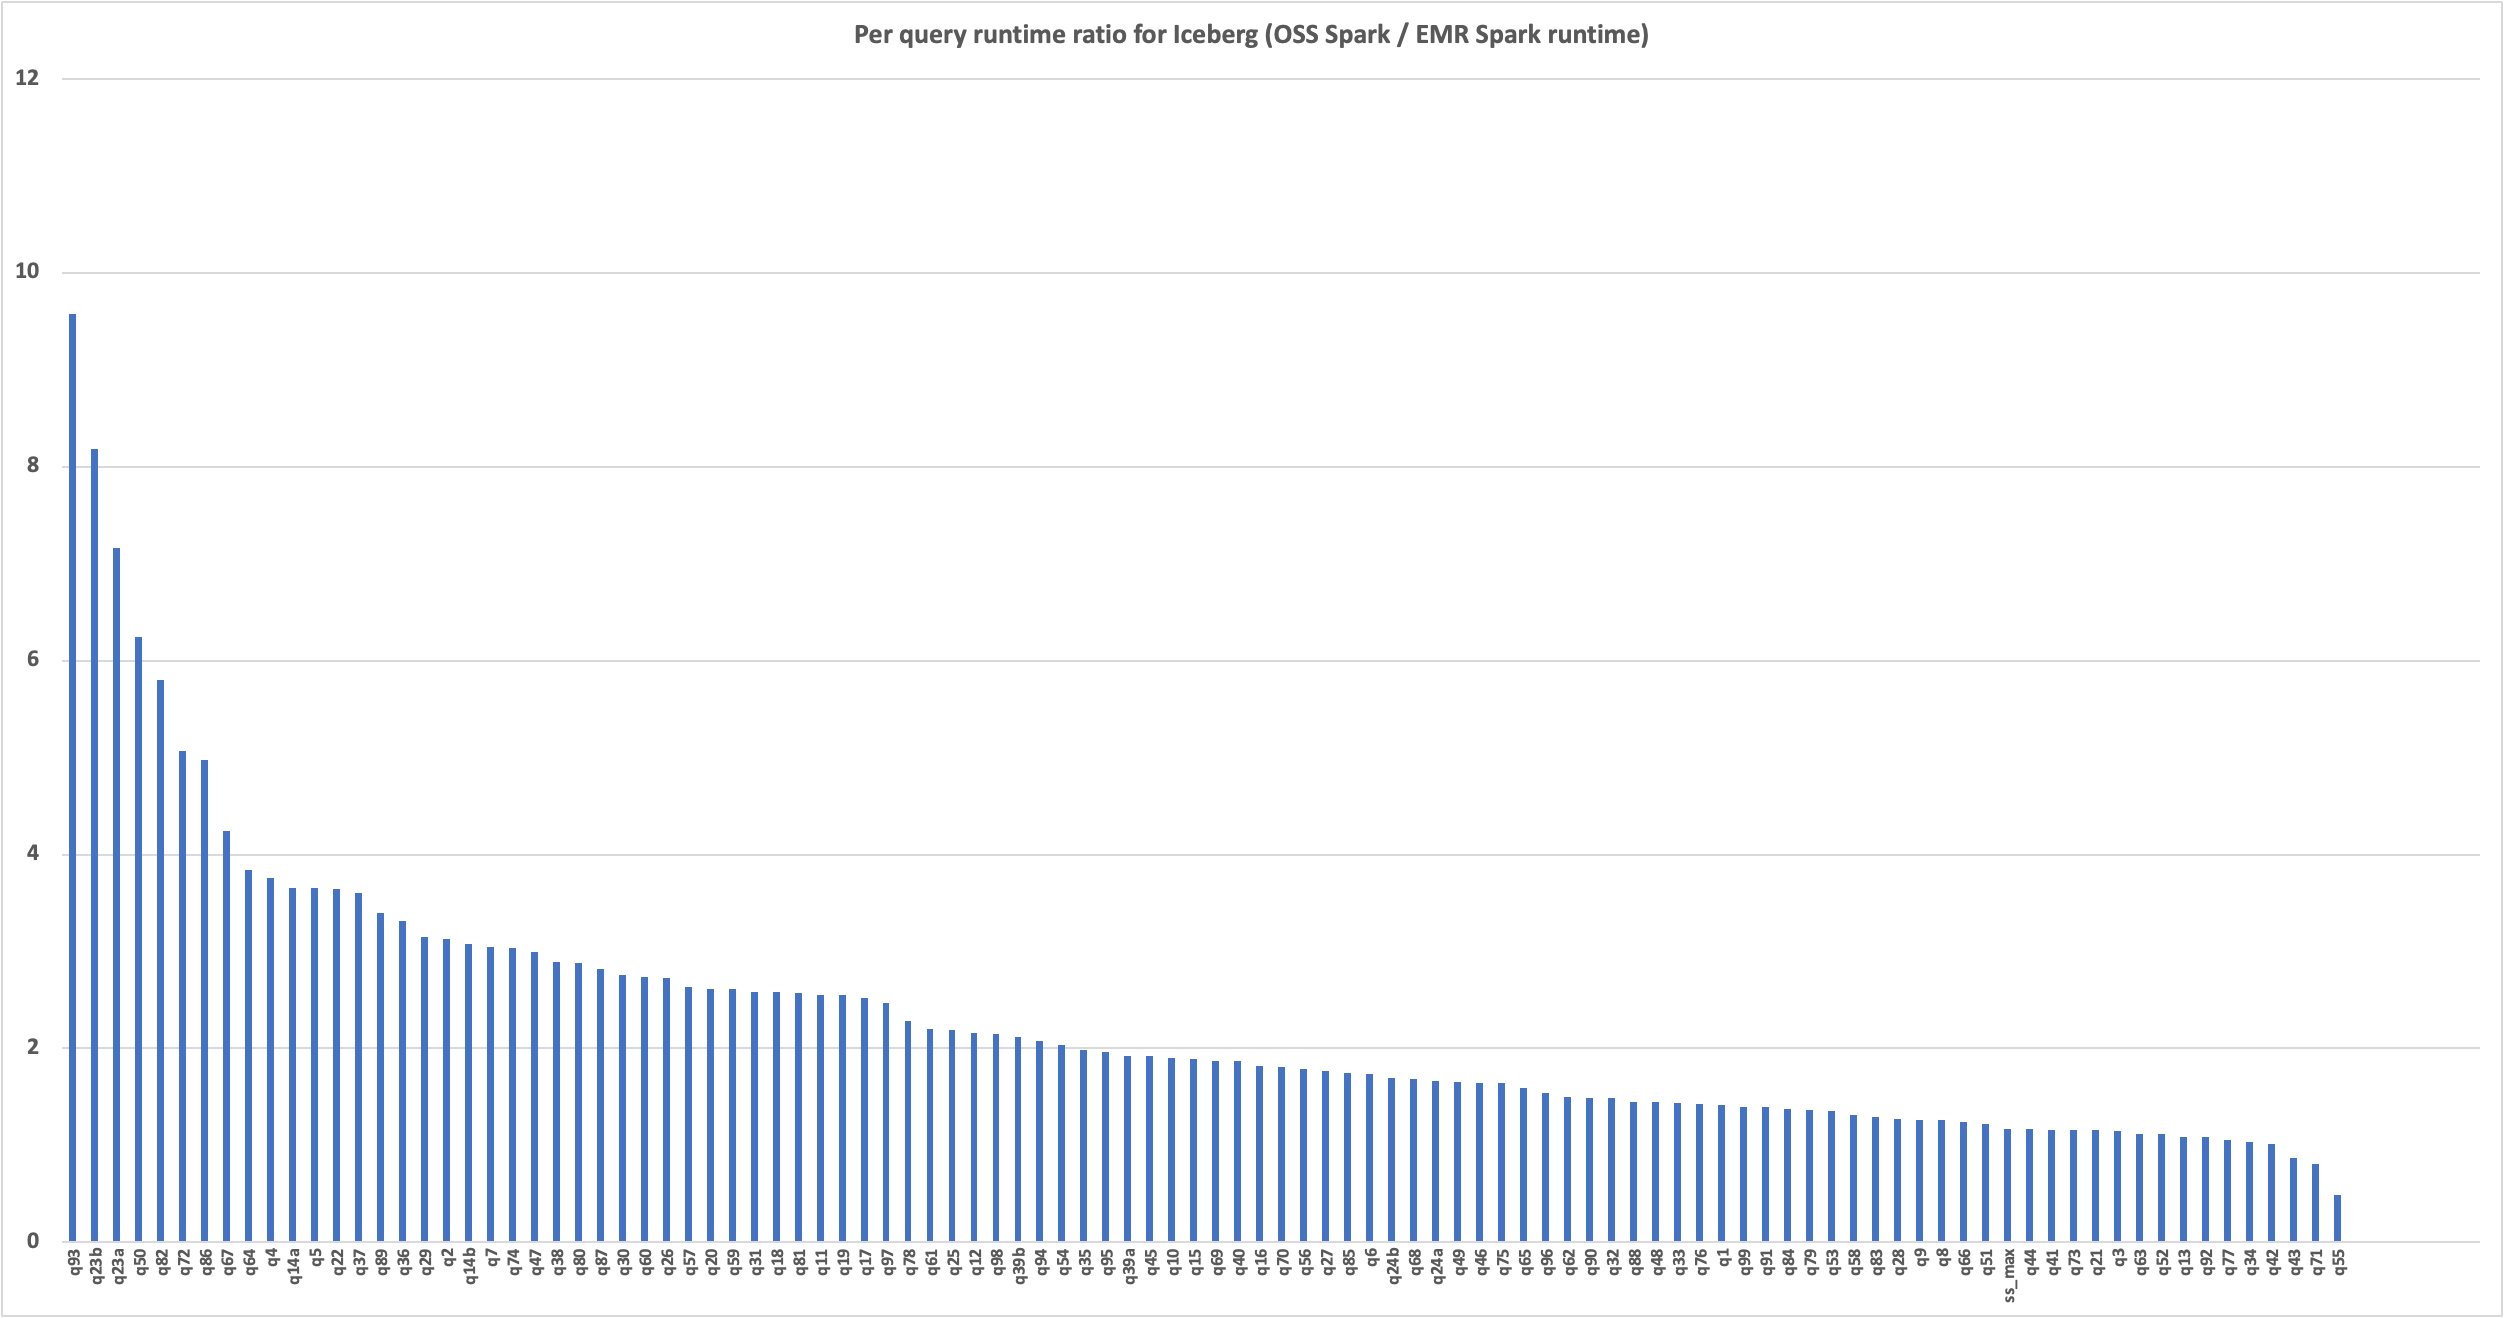
The following chart demonstrates the per-query performance improvement of Amazon EMR 7.5 relative to open source Spark 3.5.3 and Iceberg 1.6.1. The extent of the speedup varies from one query to another, with the fastest up to 9.4 times faster for q93, with Amazon EMR outperforming open source Spark with Iceberg tables. The horizontal axis arranges the TPC-DS 3TB benchmark queries in descending order based on the performance improvement seen with Amazon EMR, and the vertical axis depicts the magnitude of this speedup as a ratio.

EMR vs OSS per query cost

Cost comparison

Our benchmark provides the total runtime and geometric mean data to assess the performance of Spark and Iceberg in a complex, real-world decision support scenario. For additional insights, we also examine the cost aspect. We calculate cost estimates using formulas that account for EC2 On-Demand instances, Amazon Elastic Block Store (Amazon EBS), and Amazon EMR expenses.

  • Amazon EC2 cost (includes SSD cost) = number of instances * r5d.4xlarge hourly rate * job runtime in hours
    • r5d.4xlarge hourly rate = $1.152 per hour in us-east-1
  • Root Amazon EBS cost = number of instances * Amazon EBS per GB-hourly rate * root EBS volume size * job runtime in hours
  • Amazon EMR cost = number of instances * r5d.4xlarge Amazon EMR cost * job runtime in hours
    • 4xlarge Amazon EMR cost = $0.27 per hour
  • Total cost = Amazon EC2 cost + root Amazon EBS cost + Amazon EMR cost

The calculations reveal that the Amazon EMR 7.5 benchmark yields a 2.9-fold cost efficiency improvement over open source Spark 3.5.3 and Iceberg 1.6.1 in running the benchmark job.

Metric Amazon EMR 7.5 Amazon EMR 7.1 Open Source Spark 3.5.1 and Iceberg 1.5.2
Runtime in hours 0.426 0.564 1.540

Number of EC2 instances

(Includes primary node)

9 9 9
Amazon EBS Size 20gb 20gb 20gb

Amazon EC2

(Total runtime cost)

$4.35 $5.81 $15.97
Amazon EBS cost $0.01 $0.01 $0.04
Amazon EMR cost $1.02 $1.36 $0
Total cost $5.38 $7.18 $16.01
Cost savings Amazon EMR 7.5 is 2.9 times better Amazon EMR 7.1 is 2.2 times better Baseline

In addition to the time-based metrics discussed so far, data from Spark event logs show that Amazon EMR scanned approximately 3.4 times less data from Amazon S3 and 4.1 times fewer records than the open source version in the TPC-DS 3 TB benchmark. This reduction in Amazon S3 data scanning contributes directly to cost savings for Amazon EMR workloads.

Run open source Spark benchmarks on Iceberg tables

We used separate EC2 clusters, each equipped with nine r5d.4xlarge instances, for testing both open source Spark 3.5.3 and Amazon EMR 7.5 for Iceberg workload. The primary node was equipped with 16 vCPU and 128 GB of memory, and the eight worker nodes together had 128 vCPU and 1024 GB of memory. We conducted tests using the Amazon EMR default settings to showcase the typical user experience and minimally adjusted the settings of Spark and Iceberg to maintain a balanced comparison.

The following table summarizes the Amazon EC2 configurations for the primary node and eight worker nodes of type r5d.4xlarge.

EC2 Instance vCPU Memory (GiB) Instance Storage (GB) EBS Root Volume (GB)
r5d.4xlarge 16 128 2 x 300 NVMe SSD 20 GB

Prerequisites

The following prerequisites are required to run the benchmarking:

  1. Using the instructions in the emr-spark-benchmark GitHub repo, set up the TPC-DS source data in your S3 bucket and on your local computer.
  2. Build the benchmark application following the steps provided in Steps to build spark-benchmark-assembly application and copy the benchmark application to your S3 bucket. Alternatively, copy spark-benchmark-assembly-3.5.3.jar to your S3 bucket.
  3. Create Iceberg tables from the TPC-DS source data. Follow the instructions on GitHub to create Iceberg tables using the Hadoop catalog. For example, the following code uses an EMR 7.5 cluster with Iceberg enabled to create the tables:
aws emr add-steps 
--cluster-id <cluster-id> --steps Type=Spark,Name="Create Iceberg Tables",
Args=[--class,com.amazonaws.eks.tpcds.CreateIcebergTables,--conf,spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions,
--conf,spark.sql.catalog.hadoop_catalog=org.apache.iceberg.spark.SparkCatalog,
--conf,spark.sql.catalog.hadoop_catalog.type=hadoop,
--conf,spark.sql.catalog.hadoop_catalog.warehouse=s3://<bucket>/<warehouse_path>/,
--conf,spark.sql.catalog.hadoop_catalog.io-impl=org.apache.iceberg.aws.s3.S3FileIO,
s3://<bucket>/<jar_location>/spark-benchmark-assembly-3.5.3.jar,s3://blogpost-sparkoneks-us-east-1/blog/BLOG_TPCDS-TEST-3T-partitioned/,
/home/hadoop/tpcds-kit/tools,parquet,3000,true,<database_name>,true,true],ActionOnFailure=CONTINUE --region <AWS region>

Note the Hadoop catalog warehouse location and database name from the preceding step. We use the same iceberg tables to run benchmarks with Amazon EMR 7.5 and open source Spark.

This benchmark application is built from the branch tpcds-v2.13_iceberg. If you’re building a new benchmark application, switch to the correct branch after downloading the source code from the GitHub repo.

Create and configure a YARN cluster on Amazon EC2

To compare Iceberg performance between Amazon EMR on Amazon EC2 and open source Spark on Amazon EC2, follow the instructions in the emr-spark-benchmark GitHub repo to create an open source Spark cluster on Amazon EC2 using Flintrock with eight worker nodes.

Based on the cluster selection for this test, the following configurations are used:

Make sure to replace the placeholder <private ip of primary node>, in the yarn-site.xml file, with the primary node’s IP address of your Flintrock cluster.

Run the TPC-DS benchmark with Spark 3.5.3 and Iceberg 1.6.1

Complete the following steps to run the TPC-DS benchmark:

  1. Log in to the open source cluster primary node using flintrock login $CLUSTER_NAME.
  2. Submit your Spark job:
    1. Choose the correct Iceberg catalog warehouse location and database that has the created Iceberg tables.
    2. The results are created in s3://<YOUR_S3_BUCKET>/benchmark_run.
    3. You can track progress in /media/ephemeral0/spark_run.log.
spark-submit \
--master yarn \
--deploy-mode client \
--class com.amazonaws.eks.tpcds.BenchmarkSQL \
--conf spark.driver.cores=4 \
--conf spark.driver.memory=10g \
--conf spark.executor.cores=16 \
--conf spark.executor.memory=100g \
--conf spark.executor.instances=8 \
--conf spark.network.timeout=2000 \
--conf spark.executor.heartbeatInterval=300s \
--conf spark.dynamicAllocation.enabled=false \
--conf spark.shuffle.service.enabled=false \
--conf spark.hadoop.fs.s3a.aws.credentials.provider=com.amazonaws.auth.InstanceProfileCredentialsProvider \
--conf spark.hadoop.fs.s3.impl=org.apache.hadoop.fs.s3a.S3AFileSystem \
--conf spark.jars.packages=org.apache.hadoop:hadoop-aws:3.3.4,org.apache.iceberg:iceberg-spark-runtime-3.5_2.12:1.6.1,org.apache.iceberg:iceberg-aws-bundle:1.6.1 \
--conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions   \
--conf spark.sql.catalog.local=org.apache.iceberg.spark.SparkCatalog    \
--conf spark.sql.catalog.local.type=hadoop  \
--conf spark.sql.catalog.local.warehouse=s3a://<YOUR_S3_BUCKET>/<warehouse_path>/ \
--conf spark.sql.defaultCatalog=local   \
--conf spark.sql.catalog.local.io-impl=org.apache.iceberg.aws.s3.S3FileIO   \
spark-benchmark-assembly-3.5.3.jar   \
s3://<YOUR_S3_BUCKET>/benchmark_run 3000 1 false  \
q1-v2.13,q10-v2.13,q11-v2.13,q12-v2.13,q13-v2.13,q14a-v2.13,q14b-v2.13,q15-v2.13,q16-v2.13,\
q17-v2.13,q18-v2.13,q19-v2.13,q2-v2.13,q20-v2.13,q21-v2.13,q22-v2.13,q23a-v2.13,q23b-v2.13,\
q24a-v2.13,q24b-v2.13,q25-v2.13,q26-v2.13,q27-v2.13,q28-v2.13,q29-v2.13,q3-v2.13,q30-v2.13,\
q31-v2.13,q32-v2.13,q33-v2.13,q34-v2.13,q35-v2.13,q36-v2.13,q37-v2.13,q38-v2.13,q39a-v2.13,\
q39b-v2.13,q4-v2.13,q40-v2.13,q41-v2.13,q42-v2.13,q43-v2.13,q44-v2.13,q45-v2.13,q46-v2.13,\
q47-v2.13,q48-v2.13,q49-v2.13,q5-v2.13,q50-v2.13,q51-v2.13,q52-v2.13,q53-v2.13,q54-v2.13,\
q55-v2.13,q56-v2.13,q57-v2.13,q58-v2.13,q59-v2.13,q6-v2.13,q60-v2.13,q61-v2.13,q62-v2.13,\
q63-v2.13,q64-v2.13,q65-v2.13,q66-v2.13,q67-v2.13,q68-v2.13,q69-v2.13,q7-v2.13,q70-v2.13,\
q71-v2.13,q72-v2.13,q73-v2.13,q74-v2.13,q75-v2.13,q76-v2.13,q77-v2.13,q78-v2.13,q79-v2.13,\
q8-v2.13,q80-v2.13,q81-v2.13,q82-v2.13,q83-v2.13,q84-v2.13,q85-v2.13,q86-v2.13,q87-v2.13,\
q88-v2.13,q89-v2.13,q9-v2.13,q90-v2.13,q91-v2.13,q92-v2.13,q93-v2.13,q94-v2.13,q95-v2.13,\
q96-v2.13,q97-v2.13,q98-v2.13,q99-v2.13,ss_max-v2.13    \
true <database> > /media/ephemeral0/spark_run.log 2>&1 &!

Summarize the results

After the Spark job finishes, retrieve the test result file from the output S3 bucket at s3://<YOUR_S3_BUCKET>/benchmark_run/timestamp=xxxx/summary.csv/xxx.csv. This can be done either through the Amazon S3 console by navigating to the specified bucket location or by using the AWS Command Line Interface (AWS CLI). The Spark benchmark application organizes the data by creating a timestamp folder and placing a summary file within a folder labeled summary.csv. The output CSV files contain four columns without headers:

  • Query name
  • Median time
  • Minimum time
  • Maximum time

With the data from three separate test runs with one iteration each time, we can calculate the average and geometric mean of the benchmark runtimes.

Run the TPC-DS benchmark with the EMR runtime for Spark

Most of the instructions are similar to Steps to run Spark Benchmarking with a few Iceberg-specific details.

Prerequisites

Complete the following prerequisite steps:

  1. Run aws configure to configure the AWS CLI shell to point to the benchmarking AWS account. Refer to Configure the AWS CLI for instructions.
  2. Upload the benchmark application JAR file to Amazon S3.

Deploy the EMR cluster and run the benchmark job

Complete the following steps to run the benchmark job:

  1. Use the AWS CLI command as shown in Deploy EMR on EC2 Cluster and run benchmark job to spin up an EMR on EC2 cluster. Make sure to enable Iceberg. See Create an Iceberg cluster for more details. Choose the correct Amazon EMR version, root volume size, and same resource configuration as the open source Flintrock setup. Refer to create-cluster for a detailed description of the AWS CLI options.
  2. Store the cluster ID from the response. We need this for the next step.
  3. Submit the benchmark job in Amazon EMR using add-steps from the AWS CLI:
    1. Replace <cluster ID> with the cluster ID from Step 2.
    2. The benchmark application is at s3://<your-bucket>/spark-benchmark-assembly-3.5.3.jar.
    3. Choose the correct Iceberg catalog warehouse location and database that has the created Iceberg tables. This should be the same as the one used for the open source TPC-DS benchmark run.
    4. The results will be in s3://<your-bucket>/benchmark_run.
aws emr add-steps   --cluster-id <cluster-id>
--steps Type=Spark,Name="SPARK Iceberg EMR TPCDS Benchmark Job",
Args=[--class,com.amazonaws.eks.tpcds.BenchmarkSQL,
--conf,spark.driver.cores=4,
--conf,spark.driver.memory=10g,
--conf,spark.executor.cores=16,
--conf,spark.executor.memory=100g,
--conf,spark.executor.instances=8,
--conf,spark.network.timeout=2000,
--conf,spark.executor.heartbeatInterval=300s,
--conf,spark.dynamicAllocation.enabled=false,
--conf,spark.shuffle.service.enabled=false,
--conf,spark.sql.iceberg.data-prefetch.enabled=true,
--conf,spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions,
--conf,spark.sql.catalog.local=org.apache.iceberg.spark.SparkCatalog,
--conf,spark.sql.catalog.local.type=hadoop,
--conf,spark.sql.catalog.local.warehouse=s3://<your-bucket>/<warehouse-path>,
--conf,spark.sql.defaultCatalog=local,
--conf,spark.sql.catalog.local.io-impl=org.apache.iceberg.aws.s3.S3FileIO,
s3://<your-bucket>/spark-benchmark-assembly-3.5.3.jar,
s3://<your-bucket>/benchmark_run,3000,1,false,
'q1-v2.13\,q10-v2.13\,q11-v2.13\,q12-v2.13\,q13-v2.13\,q14a-v2.13\,q14b-v2.13\,q15-v2.13\,q16-v2.13\,q17-v2.13\,q18-v2.13\,q19-v2.13\,q2-v2.13\,q20-v2.13\,q21-v2.13\,q22-v2.13\,q23a-v2.13\,q23b-v2.13\,q24a-v2.13\,q24b-v2.13\,q25-v2.13\,q26-v2.13\,q27-v2.13\,q28-v2.13\,q29-v2.13\,q3-v2.13\,q30-v2.13\,q31-v2.13\,q32-v2.13\,q33-v2.13\,q34-v2.13\,q35-v2.13\,q36-v2.13\,q37-v2.13\,q38-v2.13\,q39a-v2.13\,q39b-v2.13\,q4-v2.13\,q40-v2.13\,q41-v2.13\,q42-v2.13\,q43-v2.13\,q44-v2.13\,q45-v2.13\,q46-v2.13\,q47-v2.13\,q48-v2.13\,q49-v2.13\,q5-v2.13\,q50-v2.13\,q51-v2.13\,q52-v2.13\,q53-v2.13\,q54-v2.13\,q55-v2.13\,q56-v2.13\,q57-v2.13\,q58-v2.13\,q59-v2.13\,q6-v2.13\,q60-v2.13\,q61-v2.13\,q62-v2.13\,q63-v2.13\,q64-v2.13\,q65-v2.13\,q66-v2.13\,q67-v2.13\,q68-v2.13\,q69-v2.13\,q7-v2.13\,q70-v2.13\,q71-v2.13\,q72-v2.13\,q73-v2.13\,q74-v2.13\,q75-v2.13\,q76-v2.13\,q77-v2.13\,q78-v2.13\,q79-v2.13\,q8-v2.13\,q80-v2.13\,q81-v2.13\,q82-v2.13\,q83-v2.13\,q84-v2.13\,q85-v2.13\,q86-v2.13\,q87-v2.13\,q88-v2.13\,q89-v2.13\,q9-v2.13\,q90-v2.13\,q91-v2.13\,q92-v2.13\,q93-v2.13\,q94-v2.13\,q95-v2.13\,q96-v2.13\,q97-v2.13\,q98-v2.13\,q99-v2.13\,ss_max-v2.13',
true,<database>],ActionOnFailure=CONTINUE --region <aws-region>

Summarize the results

After the step is complete, you can see the summarized benchmark result at s3://<YOUR_S3_BUCKET>/benchmark_run/timestamp=xxxx/summary.csv/xxx.csv in the same way as the previous run and compute the average and geometric mean of the query runtimes.

Clean up

To prevent any future charges, delete the resources you created by following the instructions provided in the Cleanup section of the GitHub repository.

Summary

Amazon EMR is consistently enhancing the EMR runtime for Spark when used with Iceberg tables, achieving a performance that is 3.6 times faster than open source Spark 3.5.3 and Iceberg 1.6.1 with EMR 7.5 on TPC-DS 3 TB, v2.13. This is a further increase of 32% from EMR 7.1. We encourage you to keep up to date with the latest Amazon EMR releases to fully benefit from ongoing performance improvements.

To stay informed, subscribe to the AWS Big Data Blog’s RSS feed, where you can find updates on the EMR runtime for Spark and Iceberg, as well as tips on configuration best practices and tuning recommendations.


About the Authors

Atul Felix Payapilly is a software development engineer for Amazon EMR at Amazon Web Services.

Udit Mehrotra is an Engineering Manager for EMR at Amazon Web Services.

Run Apache Spark Structured Streaming jobs at scale on Amazon EMR Serverless

Post Syndicated from Anubhav Awasthi original https://aws.amazon.com/blogs/big-data/run-apache-spark-structured-streaming-jobs-at-scale-on-amazon-emr-serverless/

As data is generated at an unprecedented rate, streaming solutions have become essential for businesses seeking to harness near real-time insights. Streaming data—from social media feeds, IoT devices, e-commerce transactions, and more—requires robust platforms that can process and analyze data as it arrives, enabling immediate decision-making and actions.

This is where Apache Spark Structured Streaming comes into play. It offers a high-level API that simplifies the complexities of streaming data, allowing developers to write streaming jobs as if they were batch jobs, but with the power to process data in near real time. Spark Structured Streaming integrates seamlessly with various data sources, such as Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Amazon Kinesis Data Streams, providing a unified solution that supports complex operations like windowed computations, event-time aggregation, and stateful processing. By using Spark’s fast, in-memory processing capabilities, businesses can run streaming workloads efficiently, scaling up or down as needed, to derive timely insights that drive strategic and critical decisions.

The setup of a computing infrastructure to support such streaming workloads poses its challenges. Here, Amazon EMR Serverless emerges as a pivotal solution for running streaming workloads, enabling the use of the latest open source frameworks like Spark without the need for configuration, optimization, security, or cluster management.

Starting with Amazon EMR 7.1, we introduced a new job --mode on EMR Serverless called Streaming. You can submit a streaming job from the EMR Studio console or the StartJobRun API:

aws emr-serverless start-job-run \
 --application-id APPPLICATION_ID \
 --execution-role-arn JOB_EXECUTION_ROLE \
 --mode 'STREAMING' \
 --job-driver '{
     "sparkSubmit": {
         "entryPoint": "s3://streaming script",
         "entryPointArguments": ["s3://DOC-EXAMPLE-BUCKET-OUTPUT/output"],
         "sparkSubmitParameters": "--conf spark.executor.cores=4
            --conf spark.executor.memory=16g
            --conf spark.driver.cores=4
            --conf spark.driver.memory=16g
            --conf spark.executor.instances=3"
     }
 }'

In this post, we highlight some of the key enhancements introduced for streaming jobs.

Performance

The Amazon EMR runtime for Apache Spark delivers a high-performance runtime environment while maintaining 100% API compatibility with open source Spark. Additionally, we have introduced the following enhancements to provide improved support for streaming jobs.

Amazon Kinesis connector with Enhanced Fan-Out Support

Traditional Spark streaming applications reading from Kinesis Data Streams often face throughput limitations due to shared shard-level read capacity, where multiple consumers compete for the default 2 MBps per shard throughput. This bottleneck becomes particularly challenging in scenarios requiring real-time processing across multiple consuming applications.

To address this challenge, we released the open source Amazon Kinesis Data Streams Connector for Spark Structured Streaming that supports enhanced fan-out for dedicated read throughput. Compatible with both provisioned and on-demand Kinesis Data Streams, enhanced fan-out provides each consumer with dedicated throughput of 2 MBps per shard. This enables streaming jobs to process data concurrently without the constraints of shared throughput, significantly reducing latency and facilitating near real-time processing of large data streams. By eliminating competition between consumers and enhancing parallelism, enhanced fan-out provides faster, more efficient data processing, which boosts the overall performance of streaming jobs on EMR Serverless. Starting with Amazon EMR 7.1, the connector comes pre-packaged on EMR Serverless, so you don’t need to build or download any packages.

The following diagram illustrates the architecture using shared throughput.

The following diagram illustrates the architecture using enhanced fan-out and dedicated throughput.

Refer to Build Spark Structured Streaming applications with the open source connector for Amazon Kinesis Data Streams for additional details on this connector.

Cost optimization

EMR Serverless charges are based on the total vCPU, memory, and storage resources utilized during the time workers are active, from when they are ready to execute tasks until they stop. To optimize costs, it is crucial to scale streaming jobs effectively. We have introduced the following enhancements to improve scaling at both the task level and across multiple tasks.

Fine-Grained Scaling

In practical scenarios, data volumes can be unpredictable and exhibit sudden spikes, necessitating a platform capable of dynamically adjusting to workload changes. EMR Serverless eliminates the risks of over- or under-provisioning resources for your streaming workloads. EMR Serverless scaling uses Spark dynamic allocation to correctly scale the executors according to demand. The scalability of a streaming job is also influenced by its data source to make sure Kinesis shards or Kafka partitions are also scaled accordingly. Each Kinesis shard and Kafka partition corresponds to a single Spark executor core. To achieve optimal throughput, use a one-to-one ratio of Spark executor cores to Kinesis shards or Kafka partitions.

Streaming operates through a sequence of micro-batch processes. In cases of short-running tasks, overly aggressive scaling can lead to resource wastage due to the overhead of allocating executors. To mitigate this, consider modifying spark.dynamicAllocation.executorAllocationRatio. The scaling down process is shuffle aware, avoiding executors holding shuffle data. Although this shuffle data is usually subject to garbage collection, if it’s not being cleared fast enough, the spark.dynamicAllocation.shuffleTracking.timeout setting can be adjusted to determine when executors should be timed out and removed.

Let’s examine fine-grained scaling with an example of a spiky workload where data is periodically ingested, followed by idle intervals. The following graph illustrates an EMR Serverless streaming job processing data from an on-demand Kinesis data stream. Initially, the job handles 100 records per second. As tasks queue, dynamic allocation adds capacity, which is quickly released due to short task durations (adjustable using executorAllocationRatio). When we increase input data to 10,000 records per second, Kinesis adds shards, triggering EMR Serverless to provision more executors. Scaling down happens as executors complete processing and are released after the idle timeout (spark.dynamicAllocation.executorIdleTimeout, default 60 seconds), leaving only the Spark driver running during the idle window. (Full scale-down is source dependent. For example, a provisioned Kinesis data stream with a fixed number of shards may have limitations in fully scaling down even when shards are idle.) This pattern repeats as bursts of 10,000 records per second alternate with idle periods, allowing EMR Serverless to scale resources dynamically. This job uses the following configuration:

--conf spark.dynamicAllocation.shuffleTracking.timeout=300s
--conf spark.dynamicAllocation.executorAllocationRatio=0.7

Resiliency

EMR Serverless ensures resiliency in streaming jobs by leveraging automatic recovery and fault-tolerant architectures

Built-in Availability Zone resiliency

Streaming applications drive critical business operations like fraud detection, real-time analytics, and monitoring systems, making any downtime particularly costly. Infrastructure failures at the Availability Zone level can cause significant disruptions to distributed streaming applications, potentially leading to extended downtime and data processing delays.

Amazon EMR Serverless now addresses this challenge with built-in Availability Zone failover capabilities: jobs are initially provisioned in a randomly selected Availability Zone, and, in the event of an Availability Zone failure, the service automatically retries the job in a healthy Availability Zone, minimizing interruptions to processing. Although this feature greatly enhances application reliability, achieving full resiliency requires input data sources that also support Availability Zone failover. Additionally, if you’re using a custom virtual private cloud (VPC) configuration, it is recommended to configure EMR Serverless to operate across multiple Availability Zones to optimize fault tolerance.

The following diagram illustrates a sample architecture.

Auto retry

Streaming applications are susceptible to various runtime failures caused by transient issues such as network connectivity problems, memory pressure, or resource constraints. Without proper retry mechanisms, these temporary failures can lead to permanently stopping jobs, requiring manual intervention to restart the jobs. This not only increases operational overhead but also risks data loss and processing gaps, especially in continuous data processing scenarios where maintaining data consistency is crucial.

EMR Serverless streamlines this process by automatically retrying failed jobs. Streaming jobs use checkpointing to periodically save the computation state to Amazon Simple Storage Service (Amazon S3), allowing failed jobs to restart from the last checkpoint, minimizing data loss and reprocessing time. Although there is no cap on the total number of retries, a thrash prevention mechanism allows you to configure the number of retry attempts per hour, ranging from 1–10, with the default being set to five attempts per hour.

See the following example code:

aws emr-serverless start-job-run \
 --application-id <APPPLICATION_ID>  \
 --execution-role-arn <JOB_EXECUTION_ROLE> \
 --mode 'STREAMING' \
 --retry-policy '{
    "maxFailedAttemptsPerHour": 5
 }'
 --job-driver '{
    "sparkSubmit": {
         "entryPoint": "/usr/lib/spark/examples/jars/spark-examples-does-not-exist.jar",
         "entryPointArguments": ["1"],
         "sparkSubmitParameters": "--class org.apache.spark.examples.SparkPi"
    }
 }'

Observability

EMR Serverless provides robust log management and enhanced monitoring, enabling users to efficiently troubleshoot issues and optimize the performance of streaming jobs.

Event log rotation and compression

Spark streaming applications continuously process data and generate substantial amounts of event log data. The accumulation of these logs can consume significant disk space, potentially leading to degraded performance or even system failures due to disk space exhaustion.

Log rotation mitigates these risks by periodically archiving old logs and creating new ones, thereby maintaining a manageable size of active log files. Event log rotation is enabled by default for both batch as well as streaming jobs and can’t be disabled. Rotating logs doesn’t affect the logs uploaded to the S3 bucket. However, they will be compressed using zstd standard. You can find rotated event logs under the following S3 folder:

<S3-logUri>/applications/<application-id>/jobs/<job-id>/sparklogs/

The following table summarizes key configurations that govern event log rotation.

Configuration Value Comment
spark.eventLog.rotation.enabled TRUE
spark.eventLog.rotation.interval 300 seconds Specifies time interval for the log rotation
spark.eventLog.rotation.maxFilesToRetain 2 Specifies how many rotated log files to keep during cleanup
spark.eventLog.rotation.minFileSize 1 MB Specifies a minimum file size to rotate the log file

Application log rotation and compression

One of the most common errors in Spark streaming applications is the no space left on disk errors, primarily caused by the rapid accumulation of application logs during continuous data processing. These Spark streaming application logs from drivers and executors can grow exponentially, quickly consuming available disk space.

To address this, EMR Serverless has introduced rotation and compression for driver and executor stderr and stdout logs. Log files are refreshed every 15 seconds and can range from 0–128 MB. You can find the latest log files at the following Amazon S3 locations:

<S3-logUri>/applications/<application-id>/jobs/<job-id>/SPARK_DRIVER/stderr.gz
<S3-logUri>/applications/<application-id>/jobs/<job-id>/SPARK_DRIVER/stdout.gz
<S3-logUri>/applications/<application-id>/jobs/<job-id>/SPARK_EXECUTOR/stderr.gz
<S3-logUri>/applications/<application-id>/jobs/<job-id>/SPARK_EXECUTOR/stdout.gz

Rotated application logs are pushed to archive available under the following Amazon S3 locations:

<S3-logUri>/applications/<application-id>/jobs/<job-id>/SPARK_DRIVER/archived/
<S3-logUri>/applications/<application-id>/jobs/<job-id>/SPARK_EXECUTOR/<executor-id>/archived/

Enhanced monitoring

Spark provides comprehensive performance metrics for drivers and executors, including JVM heap memory, garbage collection, and shuffle data, which are valuable for troubleshooting performance and analyzing workloads. Starting with Amazon EMR 7.1, EMR Serverless integrates with Amazon Managed Service for Prometheus, enabling you to monitor, analyze, and optimize your jobs using detailed engine metrics, such as Spark event timelines, stages, tasks, and executors. This integration is available when submitting jobs or creating applications. For setup details, refer to Monitor Spark metrics with Amazon Managed Service for Prometheus. To enable metrics for Structured Streaming queries, set the Spark property --conf spark.sql.streaming.metricsEnabled=true

You can also monitor and debug jobs using the Spark UI. The web UI presents a visual interface with detailed information about your running and completed jobs. You can dive into job-specific metrics and information about event timelines, stages, tasks, and executors for each job.

Service integrations

Organizations often struggle with integrating multiple streaming data sources into their data processing pipelines. Managing different connectors, dealing with varying protocols, and providing compatibility across diverse streaming platforms can be complex and time-consuming.

EMR Serverless supports Kinesis Data Streams, Amazon MSK, and self-managed Apache Kafka clusters as input data sources to read and process data in near real time.

Whereas the Kinesis Data Streams connector is natively available on Amazon EMR, the Kafka connector is an open source connector from the Spark community and is available in a Maven repository.

The following diagram illustrates a sample architecture for each connector.

Refer to Supported streaming connectors to learn more about using these connectors.

Additionally, you can refer to the aws-samples GitHub repo to set up a streaming job reading data from a Kinesis data stream. It uses the Amazon Kinesis Data Generator to generate test data.

Conclusion

Running Spark Structured Streaming on EMR Serverless offers a robust and scalable solution for real-time data processing. By taking advantage of the seamless integration with AWS services like Kinesis Data Streams, you can efficiently handle streaming data with ease. The platform’s advanced monitoring tools and automated resiliency features provide high availability and reliability, minimizing downtime and data loss. Furthermore, the performance optimizations and cost-effective serverless model make it an ideal choice for organizations looking to harness the power of near real-time analytics without the complexities of managing infrastructure.

Try out using Spark Structured Streaming on EMR Serverless for your own use case, and share your questions in the comments.


About the Authors

AAAnubhav Awasthi is a Sr. Big Data Specialist Solutions Architect at AWS. He works with customers to provide architectural guidance for running analytics solutions on Amazon EMR, Amazon Athena, AWS Glue, and AWS Lake Formation.

Kshitija Dound is an Associate Specialist Solutions Architect at AWS based in New York City, focusing on data and AI. She collaborates with customers to transform their ideas into cloud solutions, using AWS big data and AI services. In her spare time, Kshitija enjoys exploring museums, indulging in art, and embracing NYC’s outdoor scene.

Paul Min is a Solutions Architect at AWS, where he works with customers to advance their mission and accelerate their cloud adoption. He is passionate about helping customers reimagine what’s possible with AWS. Outside of work, Paul enjoys spending time with his wife and golfing.

Amazon EMR streamlines big data processing with simplified Amazon S3 Glacier access

Post Syndicated from Giovanni Matteo Fumarola original https://aws.amazon.com/blogs/big-data/amazon-emr-streamlines-big-data-processing-with-simplified-amazon-s3-glacier-access/

Amazon S3 Glacier serves several important audit use cases, particularly for organizations that need to retain data for extended periods due to regulatory compliance, legal requirements, or internal policies. S3 Glacier is ideal for long-term data retention and archiving of audit logs, financial records, healthcare information, and other compliance-related data. Its low-cost storage model makes it economically feasible to store vast amounts of historical data for extended periods of time. The data immutability and encryption features of S3 Glacier uphold the integrity and security of stored audit trails, which is crucial for maintaining a reliable chain of evidence. The service supports configurable vault lock policies, allowing organizations to enforce retention rules and prevent unauthorized deletion or modification of audit data. The integration of S3 Glacier with AWS CloudTrail also provides an additional layer of auditing for all API calls made to S3 Glacier, helping organizations monitor and log access to their archived data. These features make S3 Glacier a robust solution for organizations needing to maintain comprehensive, tamper-evident audit trails for extended periods while managing costs effectively.

S3 Glacier offers significant cost savings for data archiving and long-term backup compared to standard Amazon Simple Storage Service (Amazon S3) storage. It provides multiple storage tiers with varying access times and costs, allowing optimization based on specific needs. By implementing S3 Lifecycle policies, you can automatically transition data from more expensive Amazon S3 tiers to cost-effective S3 Glacier storage classes. Its flexible retrieval options enable further cost optimization by choosing slower, less expensive retrieval for non-urgent data. Additionally, Amazon offers discounts for data stored in S3 Glacier over extended periods, making it particularly cost-effective for long-term archival storage. These features allow organizations to substantially reduce storage costs, especially for large volumes of infrequently accessed data, while meeting compliance and regulatory requirements. For more details, see Understanding S3 Glacier storage classes for long-term data storage.

Prior to Amazon EMR 7.2, EMR clusters couldn’t directly read from or write to the S3 Glacier storage classes. This limitation made it challenging to process data stored in S3 Glacier as part of EMR jobs without first transitioning the data to a more readily accessible Amazon S3 storage class.

The inability to directly access S3 Glacier data meant that workflows involving both active data in Amazon S3 and archived data in S3 Glacier were not seamless. Users often had to implement complex workarounds or multi-step processes to include S3 Glacier data in their EMR jobs. Without built-in S3 Glacier support, organizations couldn’t take full advantage of the cost savings in S3 Glacier for large-scale data analysis tasks on historical or infrequently accessed data.

Although S3 Lifecycle policies could move data to S3 Glacier, EMR jobs couldn’t easily incorporate this archived data into their processing without manual intervention or separate data retrieval steps.

The lack of seamless S3 Glacier integration made it challenging to implement a truly unified data lake architecture that could efficiently span across hot, warm, and cold data tiers.These limitations often required users to implement complex data management strategies or accept higher storage costs to keep data readily accessible for Amazon EMR processing. The improvements in Amazon EMR 7.2 aimed to address these issues, providing more flexibility and cost-effectiveness in big data processing across various storage tiers.

In this post, we demonstrate how to set up and use Amazon EMR on EC2 with S3 Glacier for cost-effective data processing.

Solution overview

With the release of Amazon EMR 7.2.0, significant improvements have been made in handling S3 Glacier objects:

  • Improved S3A protocol support – You can now read restored S3 Glacier objects directly from Amazon S3 locations using the S3A protocol. This enhancement streamlines data access and processing workflows.
  • Intelligent S3 Glacier file handling – Starting from Amazon EMR 7.2.0+, the S3A connector can differentiate between S3 Glacier and S3 Glacier Deep Archive objects. This capability prevents AmazonS3Exceptions from occurring when attempting to access S3 Glacier objects that have a restore operation in progress.
  • Selective read operations – The new version intelligently ignores archived S3 Glacier objects that are still in the process of being restored, enhancing operational efficiency.
  • Customizable S3 Glacier object handling – A new setting, fs.s3a.glacier.read.restored.objects, offers three options for managing S3 Glacier objects:
    • READ_ALL (Default) – Amazon EMR processes all objects regardless of their storage class.
    • SKIP_ALL_GLACIER – Amazon EMR ignores S3 Glacier-tagged objects, similar to the default behavior of Amazon Athena.
    • READ_RESTORED_GLACIER_OBJECTS – Amazon EMR checks the restoration status of S3 Glacier objects. Restored objects are processed like standard S3 objects, and unrestored ones are ignored. This behavior is the same as Athena if you configure the table property as described in Query restored Amazon S3 Glacier objects.

These enhancements provide you with greater flexibility and control over how Amazon EMR interacts with S3 Glacier storage, improving both performance and cost-effectiveness in data processing workflows.

Amazon EMR 7.2.0 and later versions offer improved integration with S3 Glacier storage, enabling cost-effective data analysis on archived data. In this post, we walk through the following steps to set up and test this integration:

  1. Create an S3 bucket. This will serve as the primary storage location for your data.
  2. Load and transition data:
    • Upload your dataset to S3.
    • Use lifecycle policies to transition the data to the S3 Glacier storage class.
  3. Create an EMR Cluster. Make sure you’re using Amazon EMR version 7.2.0 or higher.
  4. Initiate data restoration by submitting a restore request for the S3 Glacier data before processing.
  5. To configure the Amazon EMR for S3 Glacier integration, set the fs.s3a.glacier.read.restored.objects property to READ_RESTORED_GLACIER_OBJECTS. This enables Amazon EMR to properly handle restored S3 Glacier objects.
  6. Run Spark queries on the restored data through Amazon EMR.

Consider the following best practices:

  • Plan workflows around S3 Glacier restore times
  • Monitor costs associated with data restoration and processing
  • Regularly review and optimize your data lifecycle policies

By implementing this integration, organizations can significantly reduce storage costs while maintaining the ability to analyze historical data when needed. This approach is particularly beneficial for large-scale data lakes and long-term data retention scenarios.

Prerequisites

The setup requires the following prerequisites:

Create an S3 bucket

Create an S3 bucket with different S3 Glacier objects as listed in the following code:

aws s3api put-object --bucket reinvent-glacier-demo --key T1/year=2024/month=1/day=1/
aws s3api put-object --bucket reinvent-glacier-demo --key T1/year=2024/month=1/day=2/

aws s3api put-object --bucket reinvent-glacier-demo --key T1/year=2023/month=1/day=1/
aws s3api put-object --bucket reinvent-glacier-demo --key T1/year=2023/month=1/day=2/

aws s3api put-object --bucket reinvent-glacier-demo --key T1/year=2022/month=1/day=1/
aws s3api put-object --bucket reinvent-glacier-demo --key T1/year=2022/month=1/day=2/

aws s3api put-object --bucket reinvent-glacier-demo --key T1/year=2021/month=1/day=1/
aws s3api put-object --bucket reinvent-glacier-demo --key T1/year=2021/month=1/day=2/

For more information, refer to Creating a bucket and Setting an S3 Lifecycle configuration on a bucket.

The following is the list of objects:

ls | sort
glacier_deep_archive_1.txt
glacier_deep_archive_2.txt
glacier_flexible_retrieval_formerly_glacier_1.txt
glacier_flexible_retrieval_formerly_glacier_2.txt
glacier_instant_retrieval_1.txt
glacier_instant_retrieval_2.txt
standard_s3_file_1.txt
standard_s3_file_2.txt

The content of the objects is as follows:

ls ./* | sort | xargs cat
Long-lived archive data accessed less than once a year with retrieval of hours
Long-lived archive data accessed once a year with retrieval of minutes to hours
Long-lived archive data accessed once a quarter with instant retrieval in milliseconds
standard s3 file 1
standard s3 file 2

S3 Glacier Instant Retrieval objects

For more information about S3 Glacier Instance Retrieval objects, see Appendix A at the end of this post. The objects are listed as follows:

glacier_instant_retrieval_1.txt
glacier_instant_retrieval_2.txt

The objects include the following contents:

Long-lived archive data accessed once a quarter with instant retrieval in milliseconds

To set different storage classes for objects in different folders, use the –storage-class parameter when uploading objects or change the storage class after upload:

aws s3 cp glacier_instant_retrieval_1.txt s3://reinvent-glacier-demo/T1/year=2023/month=1/day=1/ --storage-class GLACIER_IR

aws s3 cp glacier_instant_retrieval_2.txt s3://reinvent-glacier-demo/T1/year=2023/month=1/day=2/ --storage-class GLACIER_IR

S3 Glacier Flexible Retrieval objects

For more information about S3 Glacier Flexible Retrieval objects, see Appendix B at the end of this post. The objects are listed as follows:

glacier_flexible_retrieval_formerly_glacier_1.txt
glacier_flexible_retrieval_formerly_glacier_2.txt

The objects include the following contents:

Long-lived archive data accessed once a year with retrieval of minutes to hours

To set different storage classes for objects in different folders, use the –storage-class parameter when uploading objects or change the storage class after upload:

aws s3 cp glacier_flexible_retrieval_formerly_glacier_1.txt s3://reinvent-glacier-demo/T1/year=2022/month=1/day=1/ --storage-class GLACIER

aws s3 cp glacier_flexible_retrieval_formerly_glacier_2.txt s3://reinvent-glacier-demo/T1/year=2022/month=1/day=2/ --storage-class GLACIER

S3 Glacier Deep Archive objects

For more information about S3 Glacier Deep Archive objects, see Appendix C at the end of this post. The objects are listed as follows:

glacier_deep_archive_1.txt
glacier_deep_archive_2.txt

The objects include the following contents:

Long-lived archive data accessed less than once a year with retrieval of hours

To set different storage classes for objects in different folders, use the –storage-class parameter when uploading objects or change the storage class after upload:

aws s3 cp glacier_deep_archive_1.txt s3://reinvent-glacier-demo/T1/year=2021/month=1/day=1/ --storage-class DEEP_ARCHIVE

aws s3 cp glacier_deep_archive_2.txt s3://reinvent-glacier-demo/T1/year=2021/month=1/day=2/ --storage-class DEEP_ARCHIVE

List the bucket contents

List the bucket contents with the following code:

aws s3 ls s3://reinvent-glacier-demo/T1/ --recursive
2024-11-17 09:10:05          0 T1/year=2021/month=1/day=1/
2024-11-17 10:43:47         79 T1/year=2021/month=1/day=1/glacier_deep_archive_1.txt
2024-11-17 09:10:14          0 T1/year=2021/month=1/day=2/
2024-11-17 10:44:06         79 T1/year=2021/month=1/day=2/glacier_deep_archive_2.txt
2024-11-17 09:09:53          0 T1/year=2022/month=1/day=1/
2024-11-17 10:27:02         80 T1/year=2022/month=1/day=1/glacier_flexible_retrieval_formerly_glacier_1.txt
2024-11-17 09:09:58          0 T1/year=2022/month=1/day=2/
2024-11-17 10:27:21         80 T1/year=2022/month=1/day=2/glacier_flexible_retrieval_formerly_glacier_2.txt
2024-11-17 09:09:43          0 T1/year=2023/month=1/day=1/
2024-11-17 10:10:48         87 T1/year=2023/month=1/day=1/glacier_instant_retrieval_1.txt
2024-11-17 09:09:48          0 T1/year=2023/month=1/day=2/
2024-11-17 10:11:06         87 T1/year=2023/month=1/day=2/glacier_instant_retrieval_2.txt
2024-11-17 09:09:14          0 T1/year=2024/month=1/day=1/
2024-11-17 09:36:59         19 T1/year=2024/month=1/day=1/standard_s3_file_1.txt
2024-11-17 09:09:35          0 T1/year=2024/month=1/day=2/
2024-11-17 09:37:11         19 T1/year=2024/month=1/day=2/standard_s3_file_2.txt

Create an EMR Cluster

Complete the following steps to create an EMR Cluster:

  1. On the Amazon EMR console, choose Clusters in the navigation pane.
  2. Choose Create cluster.
  3. For the cluster type, choose Advanced configuration for more control over cluster settings.
  4. Configure the software options:
    • Choose the Amazon EMR release version (make sure it’s 7.2.0 or higher for S3 Glacier integration).
    • Choose applications (such as Spark or Hadoop).
  5. Configure the hardware options:
    • Choose the instance types for primary, core, and task nodes.
    • Choose the number of instances for each node type.
  6. Set the general cluster settings:
    • Name your cluster.
    • Choose logging options (recommended to enable logging).
    • Choose a service role for Amazon EMR.
  7. Configure the security options:
  8. Choose an EC2 key pair for SSH access.
  9. Set up an Amazon EMR role and EC2 instance profile.
  10. To configure networking, choose a VPC and subnet for your cluster.
  11. Optionally, you can add steps to run immediately when the cluster starts.
  12. Review your settings and choose Create cluster to launch your EMR Cluster.

For more information and detailed steps, see Tutorial: Getting started with Amazon EMR.

For additional resources, refer to Plan, configure and launch Amazon EMR clusters, Configure IAM service roles for Amazon EMR permissions to AWS services and resources, and Use security configurations to set up Amazon EMR cluster security.

Make sure that your EMR cluster has the necessary permissions to access Amazon S3 and S3 Glacier, and that it’s configured to work with the storage classes you plan to use in your demonstration.

Perform queries

In this section, we provide code to perform different queries.

Create a table

Use the following code to create a table:

CREATE TABLE default.reinvent_demo_table (
  data STRING,
  year INT,
  month INT,
  day INT
)
ROW FORMAT SERDE 'org.apache.hadoop.hive.serde2.lazy.LazySimpleSerDe'
WITH SERDEPROPERTIES ('serialization.format' = ',', 'field.delim' = ',')
STORED AS TEXTFILE
PARTITIONED BY (year, month, day)
LOCATION 's3a://reinvent-glacier-demo/T1';
ALTER TABLE reinvent_demo_table ADD IF NOT EXISTS
PARTITION (year=2024, month=1, day=1) LOCATION 's3a://reinvent-glacier-demo/T1/year=2024/month=1/day=1/'
PARTITION (year=2024, month=1, day=2) LOCATION 's3a://reinvent-glacier-demo/T1/year=2024/month=1/day=2/'
PARTITION (year=2023, month=1, day=1) LOCATION 's3a://reinvent-glacier-demo/T1/year=2023/month=1/day=1/'
PARTITION (year=2023, month=1, day=2) LOCATION 's3a://reinvent-glacier-demo/T1/year=2023/month=1/day=2/'
PARTITION (year=2022, month=1, day=1) LOCATION 's3a://reinvent-glacier-demo/T1/year=2022/month=1/day=1/'
PARTITION (year=2022, month=1, day=2) LOCATION 's3a://reinvent-glacier-demo/T1/year=2022/month=1/day=2/'
PARTITION (year=2021, month=1, day=1) LOCATION 's3a://reinvent-glacier-demo/T1/year=2021/month=1/day=1/'
PARTITION (year=2021, month=1, day=2) LOCATION 's3a://reinvent-glacier-demo/T1/year=2021/month=1/day=2/';

Queries before restoring S3 Glacier objects

Before you restore the S3 Glacier objects, run the following queries:

  • ·READ_ALL – The following code shows the default behavior:
$ spark-sql --conf spark.hadoop.fs.s3a.glacier.read.restored.objects=READ_ALL
spark-sql (default)> select * from reinvent_demo_table;

This option throws an exception reading the S3 Glacier storage class objects:

24/11/17 11:57:59 WARN TaskSetManager: Lost task 0.2 in stage 0.0 (TID 9)
(ip-172-31-38-56.ec2.internal executor 2): java.nio.file.AccessDeniedException:
s3a://reinvent-glacier-demo/T1/year=2022/month=1/day=1/glacier_flexible_retrieval_formerly_glacier_1.txt:
open s3a://reinvent-glacier-demo/T1/year=2022/month=1/day=1/glacier_flexible_retrieval_formerly_glacier_1.txt
at 0 on s3a://reinvent-glacier-demo/T1/year=2022/month=1/day=1/glacier_flexible_retrieval_formerly_glacier_1.txt:
software.amazon.awssdk.services.s3.model.InvalidObjectStateException:
The operation is not valid for the object's storage class
(Service: S3, Status Code: 403, Request ID: N6P6SXE6T50QATZY,
Extended Request ID: Elg7XerI+xrhI1sFb8TAhFqLrQAd9cWFG2UrKo8jgt73dFG+5UWRT6G7vkI3wWuvsjhMewuE9Gw=):
InvalidObjectState
  • SKIP_ALL_GLACIER – This option retrieves Amazon S3 Standard and S3 Glacier Instant Retrieval objects:
$ spark-sql --conf spark.hadoop.fs.s3a.glacier.read.restored.objects=SKIP_ALL_GLACIER spark-sql (default)> select * from reinvent_demo_table;

24/11/17 14:28:31 WARN SessionState: METASTORE_FILTER_HOOK will be ignored, since hive.security.authorization.manager is set to instance of HiveAuthorizerFactory.
SLF4J: Failed to load class "org.slf4j.impl.StaticLoggerBinder".
SLF4J: Defaulting to no-operation (NOP) logger implementation
SLF4J: See http://www.slf4j.org/codes.html#StaticLoggerBinder for further details.
Long-lived archive data accessed once a quarter with instant retrieval in milliseconds    2023    1    1
Long-lived archive data accessed once a quarter with instant retrieval in milliseconds    2023    1    2
standard s3 file 2    2024    1    2
standard s3 file 1    2024    1    1
Time taken: 7.104 seconds, Fetched 4 row(s)
  • READ_RESTORED_GLACIER_OBJECTS – The option retrieves standard Amazon S3 and all restored S3 Glacier objects. The S3 Glacier objects are under retrieval and will show up after they are retrieved.
spark-sql --conf spark.hadoop.fs.s3a.glacier.read.restored.objects=READ_RESTORED_GLACIER_OBJECTS

spark-sql (default)> select * from reinvent_demo_table;
24/11/17 14:31:52 WARN SessionState: METASTORE_FILTER_HOOK will be ignored, since hive.security.authorization.manager is set to instance of HiveAuthorizerFactory.
SLF4J: Failed to load class "org.slf4j.impl.StaticLoggerBinder".
SLF4J: Defaulting to no-operation (NOP) logger implementation
SLF4J: See http://www.slf4j.org/codes.html#StaticLoggerBinder for further details.
standard s3 file 2    2024    1    2
standard s3 file 1    2024    1    1
Long-lived archive data accessed once a quarter with instant retrieval in milliseconds    2023    1    1
Long-lived archive data accessed once a quarter with instant retrieval in milliseconds    2023    1    2
Time taken: 6.533 seconds, Fetched 4 row(s)

Queries after restoring S3 Glacier objects

Perform the following queries after restoring S3 Glacier objects:

  • READ_ALL – Because all the objects have been restored, all the objects are read (no exception is thrown):
$ spark-sql --conf spark.hadoop.fs.s3a.glacier.read.restored.objects=READ_ALL

spark-sql (default)> select * from reinvent_demo_table;
24/11/18 01:38:37 WARN SessionState: METASTORE_FILTER_HOOK will be ignored, since hive.security.authorization.manager is set to instance of HiveAuthorizerFactory.
SLF4J: Failed to load class "org.slf4j.impl.StaticLoggerBinder".
SLF4J: Defaulting to no-operation (NOP) logger implementation
SLF4J: See http://www.slf4j.org/codes.html#StaticLoggerBinder for further details.
Long-lived archive data accessed once a year with retrieval of minutes to hours    2022    1    2
Long-lived archive data accessed once a year with retrieval of minutes to hours    2022    1    1
Long-lived archive data accessed once a quarter with instant retrieval in milliseconds    2023    1    1
Long-lived archive data accessed once a quarter with instant retrieval in milliseconds    2023    1    2
standard s3 file 2    2024    1    2
Long-lived archive data accessed less than once a year with retrieval of hours    2021    1    1
Long-lived archive data accessed less than once a year with retrieval of hours    2021    1    2
standard s3 file 1    2024    1    1
Time taken: 6.71 seconds, Fetched 8 row(s)
  • SKIP_ALL_GLACIER – This option retrieves standard Amazon S3 and S3 Glacier Instant Retrieval objects:
$ spark-sql --conf spark.hadoop.fs.s3a.glacier.read.restored.objects=SKIP_ALL_GLACIER

spark-sql (default)> select * from reinvent_demo_table;
24/11/18 01:39:27 WARN SessionState: METASTORE_FILTER_HOOK will be ignored, since hive.security.authorization.manager is set to instance of HiveAuthorizerFactory.
SLF4J: Failed to load class "org.slf4j.impl.StaticLoggerBinder".
SLF4J: Defaulting to no-operation (NOP) logger implementation
SLF4J: See http://www.slf4j.org/codes.html#StaticLoggerBinder for further details.
Long-lived archive data accessed once a quarter with instant retrieval in milliseconds    2023    1    1
standard s3 file 1    2024    1    1
standard s3 file 2    2024    1    2
Long-lived archive data accessed once a quarter with instant retrieval in milliseconds    2023    1    2
Time taken: 6.898 seconds, Fetched 4 row(s)
  • READ_RESTORED_GLACIER_OBJECTS – The option retrieves standard Amazon S3 and all restored S3 Glacier objects. The S3 Glacier objects are under retrieval and will show up after they are retrieved.
$ spark-sql --conf spark.hadoop.fs.s3a.glacier.read.restored.objects=READ_RESTORED_GLACIER_OBJECTS

spark-sql (default)> select * from reinvent_demo_table;
24/11/18 01:40:55 WARN SessionState: METASTORE_FILTER_HOOK will be ignored, since hive.security.authorization.manager is set to instance of HiveAuthorizerFactory.
SLF4J: Failed to load class "org.slf4j.impl.StaticLoggerBinder".
SLF4J: Defaulting to no-operation (NOP) logger implementation
SLF4J: See http://www.slf4j.org/codes.html#StaticLoggerBinder for further details.
Long-lived archive data accessed once a year with retrieval of minutes to hours    2022    1    1
Long-lived archive data accessed less than once a year with retrieval of hours    2021    1    2
Long-lived archive data accessed once a year with retrieval of minutes to hours    2022    1    2
Long-lived archive data accessed once a quarter with instant retrieval in milliseconds    2023    1    1
standard s3 file 1    2024    1    1
standard s3 file 2    2024    1    2
Long-lived archive data accessed less than once a year with retrieval of hours    2021    1    1
Long-lived archive data accessed once a quarter with instant retrieval in milliseconds    2023    1    2
Time taken: 6.542 seconds, Fetched 8 row(s)

Conclusion

The integration of Amazon EMR with S3 Glacier storage marks a significant advancement in big data analytics and cost-effective data management. By bridging the gap between high-performance computing and long-term, low-cost storage, this integration opens up new possibilities for organizations dealing with vast amounts of historical data.

Key benefits of this solution include:

  • Cost optimization – You can take advantage of the economical storage options of S3 Glacier while maintaining the ability to perform analytics when needed
  • Data lifecycle management – You can benefit from a seamless transition of data from active S3 buckets to archival S3 Glacier storage, and back when analysis is required
  • Performance and flexibility – Amazon EMR is able to work directly with restored S3 Glacier objects, providing efficient processing of historical data without compromising on performance
  • Compliance and auditing – The integration offers enhanced capabilities for long-term data retention and analysis, which are crucial for industries with strict regulatory requirements
  • Scalability – The solution scales effortlessly, accommodating growing data volumes without significant cost increases

As data continues to grow exponentially, the Amazon EMR and S3 Glacier integration provides a powerful toolset for organizations to balance performance, cost, and compliance. It enables data-driven decision-making on historical data without the overhead of maintaining it in high-cost, readily accessible storage.

By following the steps outlined in this post, data engineers and analysts can unlock the full potential of their archived data, turning cold storage into a valuable asset for business intelligence and long-term analytics strategies.

As we move forward in the era of big data, solutions like this Amazon EMR and S3 Glacier integration will play a crucial role in shaping how organizations manage, store, and derive value from their ever-growing data assets.


About the Authors

Giovanni Matteo Fumarola is the Senior Manager for EMR Spark and Iceberg group. He is an Apache Hadoop Committer and PMC member. He has been focusing in the big data analytics space since 2013.

Narayanan Venkateswaran is an Engineer in the AWS EMR group. He works on developing Hive in EMR. He has over 17 years of work experience in the industry across several companies including Sun Microsystems, Microsoft, Amazon and Oracle. Narayanan also holds a PhD in databases with focus on horizontal scalability in relational stores.

Karthik Prabhakar is a Senior Analytics Architect for Amazon EMR at AWS. He is an experienced analytics engineer working with AWS customers to provide best practices and technical advice in order to assist their success in their data journey.


Appendix A: S3 Glacier Instant Retrieval

S3 Glacier Instant Retrieval objects store long-lived archive data accessed once a quarter with instant retrieval in milliseconds. These are not distinguished from S3 Standard object, and there is no option to restore them as well. The key difference between S3 Glacier Instant Retrieval and standard S3 object storage lies in their intended use cases, access speeds, and costs:

  • Intended use cases – Their intended use cases differ as follows:
    • S3 Glacier Instant Retrieval – Designed for infrequently accessed, long-lived data where access needs to be almost instantaneous, but lower storage costs are a priority. It’s ideal for backups or archival data that might need to be retrieved occasionally.
    • Standard S3 – Designed for frequently accessed, general-purpose data that requires quick access. It’s suited for primary, active data where retrieval speed is essential.
  • Access speed – The differences in access speed are as follows:
    • S3 Glacier Instant Retrieval – Provides millisecond access similar to standard Amazon S3, though it’s optimized for infrequent access, balancing quick retrieval with lower storage costs.
    • Standard S3 – Also offers millisecond access but without the same access frequency limitations, supporting workloads where frequent retrieval is expected.
  • Cost structure – The cost structure is as follows:
    • S3 Glacier Instant Retrieval – Lower storage cost compared to standard Amazon S3 but slightly higher retrieval costs. It’s cost-effective for data accessed less frequently.
    • Standard S3 – Higher storage cost but lower retrieval cost, making it suitable for data that needs to be frequently accessed.
  • Durability and availability – Both S3 Glacier Instant Retrieval and standard Amazon S3 maintain the same high durability (99.999999999%) but have different availability SLAs. Standard Amazon S3 generally has a slightly higher availability, whereas S3 Glacier Instant Retrieval is optimized for infrequent access and has a slightly lower availability SLA.

Appendix B: S3 Glacier Flexible Retrieval

S3 Glacier Flexible Retrieval (previously known simply as S3 Glacier) is an Amazon S3 storage class for archival data that is rarely accessed but still needs to be preserved long-term for potential future retrieval at a very low cost. It’s optimized for scenarios where occasional access to data is required but immediate access is not critical. The key differences between S3 Glacier Flexible Retrieval and standard Amazon S3 storage are as follows:

  • Intended use cases – Best for long-term data storage where data is accessed very infrequently, such as compliance archives, media assets, scientific data, and historical records.
  • Access options and retrieval speeds – The differences in access and retrieval speed are as follows:
    • Expedited – Retrieval in 1–5 minutes for urgent access (higher retrieval costs).
    • Standard – Retrieval in 3–5 hours (default and cost-effective option).
    • Bulk – Retrieval within 5–12 hours (lowest retrieval cost, suited for batch processing).
  • Cost structure – The cost structure is as follows:
    • Storage cost – Very low compared to other Amazon S3 storage classes, making it suitable for data that doesn’t require frequent access.
    • Retrieval cost – Retrieval incurs additional fees, which vary depending on the speed of access required (Expedited, Standard, Bulk).
    • Data retrieval pricing – The quicker the retrieval option, the higher the cost per GB.
  • Durability and availability – Like other Amazon S3 storage classes, S3 Glacier Flexible Retrieval has high durability (99.999999999%). However, it has lower availability SLAs compared to standard Amazon S3 classes due to its archive-focused design.
  • Lifecycle policies – You can set lifecycle policies to automatically transition objects from other Amazon S3 classes (like S3 Standard or S3 Standard-IA) to S3 Glacier Flexible Retrieval after a certain period of inactivity.

Appendix C: S3 Glacier Deep Archive

S3 Glacier Deep Archive is the lowest-cost storage class of Amazon S3, designed for data that is rarely accessed and intended for long-term retention. It’s the most cost-effective option within Amazon S3 for data that can tolerate longer retrieval times, making it ideal for deep archival storage. It’s a perfect solution for organizations with data that must be retained but not frequently accessed, such as regulatory compliance data, historical archives, and large datasets stored purely for backup. The key differences between S3 Glacier Deep Archive and standard Amazon S3 storage are as follows:

  • Intended use cases – S3 Glacier Deep Archive is ideal for data that is infrequently accessed and requires long-term retention, such as backups, compliance records, historical data, and archive data for industries with strict data retention regulations (such as finance and healthcare).
  • Access options and retrieval speeds – The differences in access and retrieval speed are as follows:
    • Standard retrieval – Data is typically available within 12 hours, intended for cases where occasional access is required.
    • Bulk retrieval – Provides data access within 48 hours, designed for very large datasets and batch retrieval scenarios with the lowest retrieval cost.
  • Cost structure – The cost structure is as follows:
    • Storage cost – S3 Glacier Deep Archive has the lowest storage costs across all Amazon S3 storage classes, making it the most economical choice for long-term, infrequently accessed data.
    • Retrieval cost – Retrieval costs are higher than more active storage classes and vary based on retrieval speed (Standard or Bulk).
    • Minimum storage duration – Data stored in S3 Glacier Deep Archive is subject to a minimum storage duration of 180 days, which helps maintain low costs for truly archival data.
  • Durability and availability – It offers the following durability and availability benefits:
    • Durability – S3 Glacier Deep Archive has 99.999999999% durability, similar to other Amazon S3 storage classes.
    • Availability – This storage class is optimized for data that doesn’t need frequent access, and so has lower availability SLAs compared to active storage classes like S3 Standard.
  • Lifecycle policies – Amazon S3 allows you to set up lifecycle policies to transition objects from other storage classes (such as S3 Standard or S3 Glacier Flexible Retrieval) to S3 Glacier Deep Archive based on the age or access frequency of the data.

Run high-availability long-running clusters with Amazon EMR instance fleets

Post Syndicated from Garima Arora original https://aws.amazon.com/blogs/big-data/run-high-availability-long-running-clusters-with-amazon-emr-instance-fleets/

AWS now supports high availability Amazon EMR on EC2 clusters with instance fleet configuration. With high availability instance fleet clusters, you now get the enhanced resiliency and fault tolerance of high availability architecture, along with the improved flexibility and intelligence in Amazon Elastic Compute Cloud (Amazon EC2) instance selection of instance fleets. Amazon EMR is a cloud big data platform for petabyte-scale data processing, interactive analysis, streaming, and machine learning (ML) using open source frameworks such as Apache Spark, Presto and Trino, and Apache Flink. Customers love the scalability and flexibility that Amazon EMR on EC2 offers. However, like most distributed systems running mission-critical workloads, high availability is a core requirement, especially for those with long-running workloads.

In this post, we demonstrate how to launch a high availability instance fleet cluster using the newly redesigned Amazon EMR console, as well as using an AWS CloudFormation template. We also go over the basic concepts of Hadoop high availability, EMR instance fleets, the benefits and trade-offs of high availability, and best practices for running resilient EMR clusters.

High availability in Hadoop

High availability (HA) provides continuous uptime and fault tolerance for a Hadoop cluster. The core components of Hadoop, like Hadoop Distributed File System (HDFS) NameNode and YARN ResourceManager, are single points of failure in clusters with a single primary node. In the event that any of them crash, the entire cluster goes down. High Availability removes this single point of failure by introducing redundant standby nodes that can quickly take over if the primary node fails.

In a high availability EMR cluster, one node serves as the active NameNode that handles client operations, and others act as standby NameNodes. The standby NameNodes constantly synchronize their state with the active one, enabling seamless failover to maintain service availability. To learn more, see Supported applications in an Amazon EMR Cluster with multiple primary nodes.

Key instance fleet differentiations

Amazon EMR recommends using the instance fleet configuration option for provisioning EC2 instances in EMR clusters because it offers a flexible and robust approach to cluster provisioning. Some key advantages include:

  • Flexible instance provisioning – Instance fleets provide a powerful and simple way to specify up to five EC2 instance types on the Amazon EMR console, or up to 30 when using the AWS Command Line Interface (AWS CLI) or API with an allocation strategy. This enhanced diversity helps optimize for cost and performance while increasing the likelihood of fulfilling capacity requirements.
  • Target capacity management – You can specify target capacities for On-Demand and Spot Instances for each fleet. Amazon EMR automatically manages the mix of instances to meet these targets, reducing operational overhead.
  • Improved availability – By spanning multiple instance types and purchasing options such as On-Demand and Spot, instance fleets are more resilient to capacity fluctuations in specific EC2 instance pools.
  • Enhanced Spot Instance handling – Instance fleets offer superior management of Spot Instances, including the ability to set timeouts and specify actions if Spot capacity can’t be provisioned.
  • Reliable cluster launches – You can configure your instance fleet to select multiple subnets for different Availability Zones, allowing Amazon EMR to find the best combination of instances and purchasing options across these zones to launch your cluster in. Amazon EMR will identify the best Availability Zone based on your configuration and available EC2 capacity and launch the cluster.

Prerequisites

Before you launch the high availability EMR instance fleet clusters, make sure you have the following:

  • Latest Amazon EMR release – We recommend that you use the latest Amazon EMR release to benefit from the highest level of resiliency and stability for your high availability clusters. High availability for instance fleets is supported with Amazon EMR releases 5.36.1, 6.8.1, 6.9.1, 6.10.1, 6.11.1, 6.12.0, and later.
  • Supported applications – High availability for instance fleets is supported for applications such as Apache Spark, Presto, Trino, and Apache Flink. Refer to Supported applications in an Amazon EMR Cluster with multiple primary nodes for the complete list of supported applications and their failover processes.

Launch a high availability instance fleet cluster using the Amazon EMR console

Complete the following steps on the Amazon EMR console to configure and launch a high availability EMR cluster with instance fleets:

  1. On the Amazon EMR console, create a new cluster.
  2. For Name, enter a name.
  3. For Amazon EMR release, choose the Amazon EMR release that supports high availability clusters with instance fleets. The setting will default to the latest available Amazon EMR release.

CreateHACluster-EMRRelease

  1. Under Cluster configuration, choose the desired instance types for the primary fleet. (You can select up to five when using the Amazon EMR console.)
  2. Select Use high availability to launch the cluster with three primary nodes.

CreateHACluster

  1. Choose the instance types and target On-Demand and Spot size for the core and task fleet according to your requirements.

InstanceFleet-CreateFleets

  1. Under Allocation strategy, select Apply allocation strategy.
    1. 1 We recommend that you select Price-capacity optimized for your allocation strategy for your cluster for faster cluster provisioning, more accurate Spot Instance allocation, and fewer Spot Instance interruptions.
  2. Under Networking, you can choose multiple subnets for different Availability Zones. This allows Amazon EMR to look across those subnets and launch the cluster in an Availability Zone that best suits your instance and purchasing option requirements.

allocationStrategy

  1. Review your cluster configuration and choose Create cluster.

Amazon EMR will launch your cluster in a few minutes. You can view the cluster details on the Amazon EMR console.
ClusterDetailPage

Launch a high availability cluster with AWS CloudFormation

To launch a high availability cluster using AWS CloudFormation, complete the following steps:

  1. Create a CloudFormation template with EMR resource type AWS::EMR::Cluster and JobFlowInstancesConfig property types MasterInstanceFleet, CoreInstanceFleet and (optional) TaskInstanceFleets. To launch a high availability cluster, configure TargetOnDemandCapacity=3, TargetSpotCapacity=0 for the primary instance fleet and weightedCapacity=1 for each instance type configured for the fleet. See the following code:
{
  "AWSTemplateFormatVersion": "2010-09-09",
  "Resources": {
    "cluster": {
      "Type": "AWS::EMR::Cluster",
      "Properties": {
        "Instances": {
          "Ec2SubnetIds": [
            "subnet-003c889b8379f42d1",
            "subnet-0382aadd4de4f5da9",
            "subnet-078fbbb77c92ab099"
          ],
          "MasterInstanceFleet": {
            "Name": "HAPrimaryFleet",
            "TargetOnDemandCapacity": 3,
            "TargetSpotCapacity": 0,
            "InstanceTypeConfigs": [
              {
                "InstanceType": "m5.xlarge",
                "WeightedCapacity": 1
              },
              {
                "InstanceType": "m5.2xlarge",
                "WeightedCapacity": 1
              },
              {
                "InstanceType": "m5.4xlarge",
                "WeightedCapacity": 1
              }
            ]
          },
          "CoreInstanceFleet": {
            "Name": "cfnCore",
            "InstanceTypeConfigs": [
              {
                "InstanceType": "m5.xlarge",
                "WeightedCapacity": 1
              },
              {
                "InstanceType": "m5.2xlarge",
                "WeightedCapacity": 2
              },
              {
                "InstanceType": "m5.4xlarge",
                "WeightedCapacity": 4
              }
            ],
            "LaunchSpecifications": {
              "SpotSpecification": {
                "TimeoutAction": "SWITCH_TO_ON_DEMAND",
                "TimeoutDurationMinutes": 20,
                "AllocationStrategy": "PRICE_CAPACITY_OPTIMIZED"
              }
            },
            "TargetOnDemandCapacity": "4",
            "TargetSpotCapacity": 0
          },
          "TaskInstanceFleets": [
            {
              "Name": "cfnTask",
              "InstanceTypeConfigs": [
                {
                  "InstanceType": "m5.xlarge",
                  "WeightedCapacity": 1
                },
                {
                  "InstanceType": "m5.2xlarge",
                  "WeightedCapacity": 2
                },
                {
                  "InstanceType": "m5.4xlarge",
                  "WeightedCapacity": 4
                }
              ],
              "LaunchSpecifications": {
                "SpotSpecification": {
                  "TimeoutAction": "SWITCH_TO_ON_DEMAND",
                  "TimeoutDurationMinutes": 20,
                  "AllocationStrategy": "PRICE_CAPACITY_OPTIMIZED"
                }
              },
              "TargetOnDemandCapacity": "0",
              "TargetSpotCapacity": 4
            }
          ]
        },
        "Name": "TestHACluster",
        "ServiceRole": "EMR_DefaultRole",
        "JobFlowRole": "EMR_EC2_DefaultRole",
        "ReleaseLabel": "emr-6.15.0",
        "PlacementGroupConfigs": [
          {
            "InstanceRole": "MASTER",
            "PlacementStrategy": "SPREAD"
          }
        ]
      }
    }
  }
}

Make sure to use an Amazon EMR release that supports high availability clusters with instance fleets.

  1. Create a CloudFormation stack with the preceding template:
aws cloudformation create-stack --stack-name HAInstanceFleetCluster --template-body file://cfn-template.json --region us-east-1
  1. Retrieve the cluster ID from the list-clusters response to use in the following steps. You can further filter this list based on filters like cluster status, creation date, and time.
aws emr list-clusters --query "Clusters[?Name=='<YourClusterName>']"
  1. Run the following describe-cluster command:
aws emr describe-cluster --cluster-id j-XXXXXXXXXXX --region us-east-1

If the high availability cluster was launched successfully, the describe-cluster response will return the state of the primary fleet as RUNNING and provisionedOnDemandCapacity as 3. By this point, all three primary nodes have been started successfully.

DescribeClusterResponse

Primary node failover with High Availability clusters

To fetch information on all EC2 instances for an instance fleet, use the list-instances command:

aws emr list-instances --cluster-id j-XXXXXXXXXXX --instance-fleet-type MASTER --region us-east-1

For high availability clusters, it will return three instances in RUNNING state for the primary fleet and other attributes like public and private DNS names.

PrimaryInstance-DescribeCluster

The following screenshot shows the instance fleet status on the Amazon EMR console.

Instancefleet status

Let’s examine two cases for primary node failover.

Case 1: One of the three primary instances is accidentally stopped

When an EC2 instance is accidentally stopped by a user, Amazon EMR detects this and performs a failover for the stopped primary node. Amazon EMR also attempts to launch a new primary node with the same private IP and DNS name to recover back the quorum. During this failover, the cluster remains fully operational, providing true resiliency to single primary node failures.

The following screenshots illustrate the instance fleet details.

InstanceFleetDetail-PrimaryInstanceTerminated

instanceFleerRecovery

This automatic recovery for primary nodes is also reflected in the MultiMasterInstanceGroupNodesRunning or MultiMasterInstanceGroupNodesRunningPercentage Amazon CloudWatch metric emitted by Amazon EMR for your cluster. The following screenshot shows an example of these metrics.

CloudwatchMetrics

Case 2: One of the three primary instances becomes unhealthy

If Amazon EMR continuously receives failures when trying to connect to a primary instance, it is deemed as unhealthy and Amazon EMR will attempt to replace it. Similar to case 1, Amazon EMR will perform a failover for the stopped primary node and also attempt to launch a new primary node with the same private IP and DNS name to recover the quorum.

UnhealthyPrimaryInstance
PrimaryInstanceFailover-2

If you list the instances for the primary fleet, the response will include information for the EC2 instance that was stopped by the user and the new primary instance that replaced it with the same private IP and DNS name.
DescribeClusterResponse-instanceFailover

The following screenshot shows an example of the CloudWatch metrics.

An instance can have connection failures for multiple reasons, including but not limited to disk space unavailable on the instance, critical cluster daemons like instance controller shut down with errors, high CPU utilization, and more. Amazon EMR is continuously improving its health monitoring criteria to better identify unhealthy nodes on an EMR cluster.

Considerations and best practices

The following are some of the key considerations and best practices for using EMR instance fleets to launch a high availability cluster with multiple primary nodes:

  • Use the latest EMR release – With the latest EMR releases, you get the highest level of resiliency and stability for your high availability EMR clusters with multiple primary nodes.
  • Configure subnets for high availability – Amazon EMR can’t replace a failed primary node if the subnet is oversubscribed (there aren’t any available private IP addresses in the subnet). This results in a cluster failure as soon as the second primary node fails. Limited availability of IP addresses in a subnet can also result in cluster launch or scaling failures. To avoid such scenarios, we recommend that you dedicate an entire subnet to an EMR cluster.
  • Configure core nodes for enhanced data availability – To minimize the risk of local HDFS data loss on your production clusters, we recommend that you set the dfs.replication parameter to 3 and launch at least four core nodes. Setting dfs.replication to 1 on clusters with fewer than four core nodes can lead to data loss if a single core node goes down. For clusters with three or fewer core nodes, set dfs.replication parameter to at least 2 to achieve sufficient HDFS data replication. For more information, see HDFS configuration.
  • Use an allocation strategy – We recommend enabling an allocation strategy option for your instance fleet cluster to provide faster cluster provisioning, more accurate Spot Instance allocation, and fewer Spot Instance interruptions.
  • Set alarms for monitoring primary nodes – You should monitor the health and status of primary nodes of your long-running clusters to maintain smooth operations. Configure alarms using CloudWatch metrics such as MultiMasterInstanceGroupNodesRunning, MultiMasterInstanceGroupNodesRunningPercentage, or MultiMasterInstanceGroupNodesRequested.
  • Integrate with EC2 placement groups – You can also choose to protect primary instances against hardware failures by using a placement group strategy for your primary fleet. This will spread the three primary instances across separate underlying hardware to avoid loss of multiple primary nodes at the same time in the event of a hardware failure. See Amazon EMR integration with EC2 placement groups for more details.

When setting up a high availability instance fleet cluster with Amazon EMR on EC2, it’s important to understand that all EMR nodes, including the three primary nodes, are launched within a single Availability Zone. Although this configuration maintains high availability within that Availability Zone, it also means that the entire cluster can’t tolerate an Availability Zone outage. To mitigate the risk of cluster failures due to Spot Instance reclamation, Amazon EMR launches the primary nodes using On-Demand instances, providing an additional layer of reliability for these critical components of the cluster.

Conclusion

This post demonstrated how you can use high availability with EMR on EC2 instance fleets to enhance the resiliency and reliability of your big data workloads. By using instance fleets with multiple primary nodes, EMR clusters can withstand failures and maintain uninterrupted operations, while providing enhanced instance diversity and better Spot capacity management within a single Availability Zone. You can quickly set up these high availability clusters using the Amazon EMR console or AWS CloudFormation, and monitor their health using CloudWatch metrics.

To learn more about the supported applications and their failover process, see Supported applications in an Amazon EMR Cluster with multiple primary nodes. To get started with this feature and launch a high availability EMR on EC2 cluster, refer to Plan and configure primary nodes.


About the Authors

Garima Arora is a Software Development Engineer for Amazon EMR at Amazon Web Services. She specializes in capacity optimization and helps build services that allow customers to run big data applications and petabyte-scale data analytics faster. When not hard at work, she enjoys reading fiction novels and watching anime.

Ravi Kumar is a Senior Product Manager Technical-ES (PMT) at Amazon Web Services, specialized in building exabyte-scale data infrastructure and analytics platforms. With a passion for building innovative tools, he helps customers unlock valuable insights from their structured and unstructured data. Ravi’s expertise lies in creating robust data foundations using open-source technologies and advanced cloud computing, that powers advanced artificial intelligence and machine learning use cases. A recognized thought leader in the field, he advances the data and AI ecosystem through pioneering solutions and collaborative industry initiatives. As a strong advocate for customer-centric solutions, Ravi constantly seeks ways to simplify complex data challenges and enhance user experiences. Outside of work, Ravi is an avid technology enthusiast who enjoys exploring emerging trends in data science, cloud computing, and machine learning.

Tarun Chanana is a Software Development Manager for Amazon EMR at Amazon Web Services.

Expand data access through Apache Iceberg using Delta Lake UniForm on AWS

Post Syndicated from Tomohiro Tanaka original https://aws.amazon.com/blogs/big-data/expand-data-access-through-apache-iceberg-using-delta-lake-uniform-on-aws/

The landscape of big data management has been transformed by the rising popularity of open table formats such as Apache Iceberg, Apache Hudi, and Linux Foundation Delta Lake. These formats, designed to address the limitations of traditional data storage systems, have become essential in modern data architectures. As organizations adopt various open table formats to suit their specific needs, the demand for interoperability between these formats has grown significantly. This interoperability is crucial for enabling seamless data access, reducing data silos, and fostering a more flexible and efficient data ecosystem.

Delta Lake UniForm is an open table format extension designed to provide a universal data representation that can be efficiently read by different processing engines. It aims to bridge the gap between various data formats and processing systems, offering a standardized approach to data storage and retrieval. With UniForm, you can read Delta Lake tables as Apache Iceberg tables. This expands data access to broader options of analytics engines.

This post explores how to start using Delta Lake UniForm on Amazon Web Services (AWS). You can learn how to query Delta Lake native tables through UniForm from different data warehouses or engines such as Amazon Redshift as an example of expanding data access to more engines.

How Delta Lake UniForm works

UniForm allows other table format clients such as Apache Iceberg to access Delta Lake tables. Under the hood, UniForm generates Iceberg metadata files (including metadata and manifest files) that are required for Iceberg clients to access the underlying data files in Delta Lake tables. Both Delta Lake and Iceberg metadata files reference the same data files. UniForm generates multiple table format metadata without duplicating the actual data files. When an Iceberg client reads a UniForm table, it first accesses the Iceberg metadata files for the UniForm table, which then allows the Iceberg client to read the underlying data files.

There are two options to use UniForm:

  • Create a new Delta Lake table with UniForm
  • Enable UniForm on your existing Delta Lake table

First, to create a new Delta Lake table enabling UniForm, you configure table properties for UniForm in a CREATE TABLE DDL query. The table properties are 'delta.universalFormat.enabledFormats'='iceberg' and 'delta.enableIcebergCompatV2'='true'. When these options are set to the CREATE TABLE query, Iceberg metadata files are generated along with Delta Lake metadata files. In addition to these options, Delta Lake table protocol versions that define supported features by the table such as delta.minReaderVersion and delta.minWriterVersion are required to be set to 2 and 7 or more respectively. For more information about the table protocol versions, refer to What is a table protocol specification? in Delta Lake public document. Appendix 1. Create a new Delta Lake table with UniForm shows an example query to create a new Delta Lake UniForm table.

You can also enable UniForm on an existing Delta Lake table. This option is suitable if you have Delta Lake tables in your environment. Enabling UniForm doesn’t affect your current operations on the Delta Lake tables. To enable UniForm on a Delta Lake table, run REORG TABLE db.existing_delta_lake_table APPLY (UPGRADE UNIFORM(ICEBERG_COMPAT_VERSION=2)). After running this query, Delta Lake automatically generates Iceberg metadata files for the Iceberg client. In the example in this post, you run this option and enable UniForm after you create a Delta Lake table.

For the information about enabling UniForm, refer to Enable Delta Lake UniForm in the Delta Lake public document. Note that the extra package (delta-iceberg) is required to create a UniForm table in AWS Glue Data Catalog. The extra package is also required to generate Iceberg metadata along with Delta Lake metadata for the UniForm table.

Example use case

A fictional company built a data lake with Delta Lake on Amazon Simple Storage Service (Amazon S3) that’s mainly used through Amazon Athena. According to its usage expansion, this company wants to expand data access to cloud-based data warehouses such as Amazon Redshift for flexible analytics use cases.

There are a few challenges to achieve this requirement. Delta Lake isn’t natively supported in Amazon Redshift. For those data warehouses, Delta Lake tables need to be converted to manifest tables, which requires additional operational overhead. You need to run the GENERATE command on Spark or use a crawler in AWS Glue to generate manifest tables, and you need to sync those manifest tables every time the Delta tables are updated.

Delta Lake UniForm can be a solution to meet this requirement. With Delta Lake UniForm, you can make the Delta Table compatible with the other open table formats such as Apache Iceberg, which is natively supported in Amazon Redshift. Users can query those Delta Lake tables as Iceberg tables through UniForm.

The following diagram describes the architectural overview to achieve that requirement.

bdb4538_solution-overview

In this tutorial, you create a Delta Lake table with a synthetic review dataset that includes different products and customer reviews and enable UniForm on that Delta Lake table to make it accessible from Amazon Redshift. Each component works as follows in this scenario:

  • Amazon EMR (Amazon EMR on EC2 cluster with Apache Spark): An Apache Spark application on an Amazon EMR cluster creates a Delta Lake table and enables UniForm on it. Only Delta Lake client can write to the Delta Lake UniForm table, making Amazon EMR act as a writer.
  • Amazon Redshift: Amazon Redshift uses Iceberg clients to read records from the Delta Lake UniForm table. It’s limited to reading records from the table and cannot write to it.
  • Amazon S3 and AWS Glue Data Catalog: These are used to manage the underlying files and the catalog of the Delta Lake UniForm table. The data and metadata files for the table are stored in an S3 bucket. The table is registered in AWS Glue Data Catalog.

Set up resources

In this section, you complete the following resource setup:

  1. Launch an AWS CloudFormation template to configure resources such as S3 buckets, an Amazon Virtual Private Cloud (Amazon VPC) and a subnet, a database for Delta Lake in Data Catalog, AWS Identity and Access Management (IAM) policy and role with required permissions for Amazon EMR Studio, and an EC2 instance profile for Amazon EMR on EC2 cluster
  2. Launch an Amazon EMR on EC2 cluster
  3. Create an Amazon EMR Studio Workspace
  4. Upload a Jupyter Notebook on Amazon EMR Studio Workspace
  5. Launch a CloudFormation template to configure Amazon Redshift Serverless and relevant subnets

Launch a CloudFormation template to configure basic resources

You use a provided CloudFormation template to set up resources to build Delta Lake UniForm environments. The template creates the following resources.

  • An S3 bucket to store the Delta Lake table data
  • An S3 bucket to store an Amazon EMR Studio Workspace metadata and configuration files
  • An IAM role for Amazon EMR Studio
  • An EC2 instance profile for Amazon EMR on EC2 cluster
  • VPC and subnet for an Amazon EMR on EC2 cluster
  • A database for a Delta Lake table in Data Catalog

Complete the following steps to deploy the resources.

  1. Choose Launch stack:

  1. For Stack name, enter delta-lake-uniform-on-aws. For the Parameters, DeltaDatabaseName, PublicSubnetForEMRonEC2, and VpcCIDRForEMRonEC2 are set by default. You can also change the default values. Then, choose Next.
  2. Choose Next.
  3. Choose I acknowledge that AWS CloudFormation might create IAM resources with custom names.
  4. Choose Submit.
  5. After the stack creation is complete, check the Outputs. The resource values are used in the following sections and in the Appendices.

Launch an Amazon EMR on EC2 cluster

Complete the following steps to create an Amazon EMR on EC2 cluster.

  1. Open the Amazon EMR on EC2 console.
  2. Choose Create cluster.
  3. Enter delta-lake-uniform-blog-post in Name and confirm choosing emr-7.3.0 as its release label.
  4. For Application bundle, select Spark 3.5.1Hadoop 3.3.6 and JupyterEnterpriseGateway 2.6.0.
  5. For AWS Glue Data Catalog settings, enable Use for Spark table metadata.
  6. For Networking, enter the values from the CloudFormation Outputs tab for VpcForEMR and PublicSubnetForEMR into Virtual private cloud (VPC) andSubnet respectively. For EC2 security groups, keep Create ElasticMapReduce-Primary for Primary node, and Create ElasticMapReduce-Core for Core and task nodes. The security groups for the Amazon EMR primary and core nodes are automatically created.
  7. For Cluster logs, enter s3://<DeltaLakeS3Bucket>/emr-cluster-logs as the Amazon S3 location. Replace <DeltaLakeS3Bucket> with the S3 bucket from the CloudFormation stack Outputs tab.
  8. For Software settings, select Load JSON from Amazon S3 and enter s3://aws-blogs-artifacts-public/artifacts/BDB-4538/config.json as the Amazon S3 location.
  9. For Amazon EMR service role in Identity and Access Management (IAM) roles section, choose Create a service role. Then, set default to Security Group. If there are existing security groups for Amazon EMR Primary and Core or Task nodes, set those security groups to Security Group.
  10. For EC2 instance profile for Amazon EMR, choose Choose an existing instance profile, and set EMRInstanceProfileRole to Instance profile.
  11. After reviewing the configuration, choose Create cluster.
  12. After the cluster status is Waiting on the Amazon EMR console, the cluster setup is complete (it approximately takes 10 minutes).

Create an Amazon EMR Studio Workspace

Complete the following steps to create an Amazon EMR Studio Workspace to use Delta Lake UniForm on Amazon EMR on EC2.

  1. Open Amazon EMR Studio console.
  2. Choose Create Studio.
  3. For Setup options, choose Custom.
  4. For Studio settings, enter delta-lake-uniform-studio as the Studio name.
  5. For S3 location for Workspace storage, choose Select existing location as a Workspace storage. The S3 location (s3://aws-emr-studio-<ACCOUNT_ID>-<REGION>-delta-lake-uniform-on-aws) can be obtained from EMRStudioS3Bucket on the CloudFormation Outputs tab. Then, choose EMRStudioRole as the IAM role (you can find the IAM Role name on the CloudFormation Outputs tab).
  6. For Workspace settings, enter delta-lake-workspace as the Workspace name.
  7. In Networking and security, choose the VPC ID and Subnet ID that you created in Launch an AWS CloudFormation template. You can obtain the VPC ID and Subnet ID from the VpcForEMR and PublicSubnetForEMR keys on the CloudFormation Outputs tab respectively.
  8. After reviewing the settings, choose Create Studio and launch Workspace.
  9. After creating the Studio Workspace is complete, you are redirected to Jupyter Notebook.

Upload Jupyter Notebook

Complete the following steps to configure a Jupyter Notebook to use Delta Lake UniForm with Amazon EMR.

  1. Download delta-lake-uniform-on-aws.ipynb.
  2. Choose the arrow icon at the top of the page and upload the Notebook you just downloaded.

  1. Choose and open the notebook (delta-lake-uniform-on-aws.ipynb) you uploaded in the left pane.
  2. After the notebook is opened, choose EMR Compute in the navigation pane.

  1. Attach the Amazon EMR on EC2 cluster you created in the previous section. Choose EMR on EC2 cluster and set the cluster you created previously to EMR on EC2 cluster, then choose Attach.
  2. After attaching the cluster is successful, Cluster is attached to the Workspace is displayed on the console.

Create a workgroup and a namespace for Amazon Redshift Serverless

For this step, you configure a workgroup and a namespace for Amazon Redshift Serverless to run queries on a Delta Lake UniForm table. You also configure two subnets in the same VPC created by the CloudFormation stack delta-lake-uniform-on-aws. To deploy the resources, complete the following steps:

  1. Choose Launch stack:

  1. For Stack name, enter redshift-serverless-for-delta-lake-uniform.
  2. For Parameters, enter the Availability Zone and an IP range for each subnet. The VPC ID is automatically retrieved from the CloudFormation stack you created in Launch an AWS CloudFormation template to configure basic resources. If you change the default subnet, note that at least one subnet needs to be the same subnet you created for the Amazon EMR on EC2 cluster (by default, the subnet for Amazon EMR on EC2 cluster is automatically retrieved during this CloudFormation stack creation). You can check the subnet for the cluster on the CloudFormation Outputs Then, choose Next.
  3. Choose Next again, and then choose Submit.
  4. After the stack creation is complete, check the CloudFormation Outputs Make a note of the two Subnet IDs on the Outputs tab to use later in Run queries from Amazon Redshift against the UniForm table.

Now you’re ready to use Delta Lake UniForm on Amazon EMR.

Enable Delta Lake UniForm

Start by creating a Delta Lake table that contains the customer review dataset. After creating the table, run REORG query to enable UniForm on the Delta Lake table.

Create a Delta Lake table

Complete the following steps to create a Delta Lake table based on a customer review dataset and review the table metadata.

  1. Return to the Jupyter Notebook connected to the Amazon EMR on EC2 cluster and run the following cell to add delta-iceberg.jar to use UniForm and configure the spark extension.

  1. Initialize the SparkSession. The following configuration is necessary to use Iceberg through UniForm. Before running the code, replace <DeltaLakeS3Bucket> with the name of the S3 bucket for Delta Lake, which you can find on the CloudFormation stack Outputs tab.

bdb4538-2_2-notebook

  1. Create a Spark DataFrame from customer reviews.

bdb4538-2_3-notebook_df

  1. Create a Delta Lake table with the customer reviews dataset. This step takes approximately 5 minutes.

bdb4538-2_4-notebook

  1. Run DESCRIBE EXTENDED {DB_TBL} in the next cell to review the table. The output includes the table schema, location, table properties, and so on.

bdb4538-2_5-notebook

The Delta Lake table creation is complete. Next, enable UniForm on this Delta Lake table.

Run REORG query to enable UniForm

To allow an Iceberg client to access the Delta Lake table you created, enable UniForm on the table. You can also create a new Delta Lake table with UniForm enabled. For more information, see Appendix 1 at the end of this post. To enable UniForm and review the table metadata, complete the following steps.

  1. Run the following query to enable UniForm on the Delta Lake table. To enable UniForm on an existing Delta Lake table, you run REORG query against the table.

bdb4539-3_1-uniform_reorg

  1. Run DESCRIBE EXTENDED {DB_TBL} in the next cell to review the table metadata and compare it from before and after enabling UniForm. The new properties, such as delta.enableIcebergCompatV2=true and delta.universalFormat.enabledFormats=iceberg, are added to the table properties.

bdb4538-3_2-uniform_metadata

  1. Run aws s3 ls s3://<DeltaLakeS3Bucket>/warehouse/ --recursive to confirm if the Iceberg table metadata is created. Replace <DeltaLakeS3Bucket> with the S3 bucket from the CloudFormation Outputs tab. The following screenshot shows the command output of table metadata and data files. You can confirm that Delta Lake UniForm generates both Iceberg metadata and Delta Lake metadata files as indicated by the red rectangles below.

bdb4538-3_3-uniform_metadata

  1. Before querying the Delta Lake UniForm table from an Iceberg client, run the following analytic query for the Delta Lake UniForm table from Amazon EMR on EC2 side, and review the reviews count by each product category.

bdb4538-3_4-uniform_query

  1. The query result shows the output of the reviews count by product_category:

Enabling UniForm on the Delta Lake table is complete, and now you can query the Delta Lake table from an Iceberg client. Next, you query the Delta Lake table as an Iceberg table from Amazon Redshift.

Run queries against the UniForm table from Amazon Redshift

In the previous section, you enabled UniForm on your existing Delta Lake table. This allows you to run queries on a Delta Lake table as if it were an Iceberg table from Amazon Redshift. In this section, you run an analytic query on the UniForm table using Amazon Redshift Serverless and add records with a new product category to the UniForm table through the Jupyter Notebook connected to the Amazon EMR on EC2 cluster. Then, you verify the added records with another analytic query from Amazon Redshift. You can confirm that Delta Lake UniForm enables Amazon Redshift to query the Delta Lake table through this section.

Query the UniForm table from Amazon Redshift Serverless

  1. Open Amazon Redshift Serverless console
  2. In Namespaces/Workgroups, select the delta-lake-uniform-namespace that you created using the CloudFormation stack.
  3. Choose Query data on the right top corner to open the Amazon Redshift query editor.
  4. After opening the editor, select the delta-lake-uniform-workgroup workgroup in the left pane.
  5. Choose Create connection.
  6. After you successfully create a connection, you can see the delta_uniform_db database and customer_review table you created in the left pane of the editor.
  7. Copy and paste the following analytic query to the editor and choose Run.
SELECT product_category, count(*) as count_by_product_category 
FROM "awsdatacatalog"."delta_uniform_db"."customer_reviews"
GROUP BY product_category ORDER BY count_by_product_category DESC
  1. The editor shows the same result of the review count by product_category as you obtained from Jupyter Notebook in Run REORG query to enable UniForm.

bdb4538-4_1-rs_result

Add new product category records into Delta Lake UniForm table from Amazon EMR

Go back to the Jupyter Notebook on Amazon EMR Workspace to add new records with a new product category (Books) into the Delta Lake UniForm table. After adding the records, query the UniForm table again from Amazon Redshift Serverless.

  1. On the Jupyter Notebook, go to Add new product category records into the UniForm table and run the following cell to load new records.

bdb4538-4_2-append_books

  1. Run the following cell and review the five records with Books as the product category. The following screenshot shows the output of this code.

bdb4538-4_3-append_listbooks

  1. Add the new reviews with Books product category. This takes around 2 minutes.

bdb4538-4_4-append_append

In the next section, you run a query on the UniForm table from Amazon Redshift Serverless to check if the new records with the Books product category have been added.

Review the added records in Delta Lake UniForm table from Amazon Redshift Serverless

To check if the result output includes the records of Books product category:

  1. On the query editor of Amazon Redshift, run the following query and check if the result output includes the records of Books product category.
SELECT product_category, count(*) as count_by_product_category 
FROM "awsdatacatalog"."delta_uniform_db"."customer_reviews"
GROUP BY product_category ORDER BY count_by_product_category DESC
  1. The following screenshot shows the output of the query you ran in the previous step. You can confirm the new product category Books has been added to the table from Amazon Redshift side.

bdb4538-4_5-rs-result
Now you can query from Amazon Redshift against the Delta Lake table by enabling Delta Lake UniForm.

Clean up resources

To clean up your resources, complete the following steps:

  1. In the Amazon EMR Workspaces console, choose Actions and then Delete to delete the workspace.
  2. Choose Delete to delete the Studio.
  3. In the Amazon EMR on EC2 console, choose Terminate to delete the Amazon EMR on EC2 cluster.
  4. In the Amazon S3 console, choose Empty to delete all objects in the following S3 buckets.
    1. The S3 bucket for Amazon EMR Studio such as aws-emr-studio-<ACCOUNT_ID>-<REGION>-delta-lake-uniform-on-aws. Replace <ACCOUNT_ID> and <REGION> with your account ID and the bucket’s region.
    2. The S3 bucket for Delta Lake tables such as delta-lake-uniform-on-aws-deltalakes3bucket-abcdefghijk.
  5. After you confirm the two buckets are empty, delete the CloudFormation stack redshift-serverless-for-delta-lake-uniform.
  6. After the first CloudFormation stack has been deleted, delete the CloudFormation stack delta-lake-uniform-on-aws.

Conclusion

Delta Lake UniForm on AWS represents an advancement in addressing the challenges of data interoperability and accessibility in modern big data architectures. By enabling Delta Lake tables to be read as Apache Iceberg tables, UniForm expands data access capabilities, allowing organizations to use a broader range of analytics engines and data warehouses such as Amazon Redshift.

The practical implications of this technology are substantial, offering new possibilities for data analysis and insights across diverse platforms. As organizations continue to navigate the complexities of big data, solutions like Delta Lake UniForm that promote interoperability and reduce data silos will become increasingly valuable.

By adopting these advanced open table formats and using cloud platforms such as AWS, organizations can build more robust and efficient data ecosystems. This approach not only enhances the value of existing data assets but also fosters a more agile and adaptable data strategy, ultimately driving innovation and improving decision-making processes in our data-driven world.

Appendix 1: Create a new Delta Lake table with UniForm

You can create a Delta Lake table with UniForm enabled using the following DDL.

CREATE TABLE IF NOT EXISTS delta_uniform_db.customer_reviews_create (
   marketplace string,
   customer_id string,
   review_id string,
   product_id string,
   product_title string,
   star_rating bigint,
   helpful_votes bigint,
   total_votes bigint,
   insight string,
   review_headline string,
   review_body string,
   review_date timestamp,
   review_year bigint,
   product_category string)
USING delta
TBLPROPERTIES ( 
   'delta.universalFormat.enabledFormats'='iceberg',
   'delta.enableIcebergCompatV2'='true',
   'delta.minReaderVersion'='2',
   'delta.minWriterVersion'='7')

Appendix 2: Run queries from Snowflake against the UniForm table

Delta Lake UniForm also allows you to run queries on a Delta Lake table from Snowflake. In this section, you run the same analytic query on the UniForm table using Snowflake as you previously did using Amazon Redshift Serverless in Run queries from Amazon Redshift against the UniForm table. Then you confirm that the query results from Snowflake match the results obtained from the Amazon Redshift Serverless query.

Configure IAM roles for Snowflake to access AWS Glue Data Catalog and Amazon S3

To query the Delta Lake UniForm table in Data Catalog from Snowflake, the following configurations are required.

  1. IAM roles: Create IAM roles for Snowflake to access Data Catalog and Amazon S3.
  2. Data Catalog integration with Snowflake: Snowflake provides two catalog options for Iceberg tables such as Using Snowflake as the Iceberg catalog and Using an external catalog such as Data Catalog. In this post, you choose AWS Glue Data Catalog as an external catalog. For information about the catalog options, refer to Iceberg catalog options in the Snowflake public documentation.
  3. An external volume creation for Amazon S3: To access the UniForm table from Snowflake, an external volume for Amazon S3 needs to be configured. With this configuration, Snowflake can connect the S3 bucket that you created for Iceberg tables. For information about the external volume, refer to Configure an external volume for Iceberg tables.

Create IAM roles for Snowflake to access AWS Glue Data Catalog and Amazon S3

Create the following two IAM roles for Snowflake to access AWS Glue Data Catalog and Amazon S3.

  • SnowflakeIcebergGlueCatalogRole: This IAM role is used for Snowflake to access the Delta Lake UniForm table in AWS Glue Data Catalog.
  • SnowflakeIcebergS3Role: This IAM role is used for Snowflake to access the table’s underlying data in the S3 bucket.

To configure the IAM roles, complete the following steps:

  1. Choose Launch stack:

  1. Enter snowflake-iceberg as the stack name and choose Next.
  2. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names.
  3. Choose Submit.
  4. After the stack creation is complete, check the CloudFormation Outputs tab. Make a note of the names and ARNs of the two IAM roles, which are used in the following section.

Create an AWS Glue Data Catalog Integration

Create a catalog integration for AWS Glue Data Catalog. For more information about the catalog integration for AWS Glue Data Catalog, refer to Configure a catalog integration for AWS Glue in the Snowflake public documentation. To configure the catalog integration, complete the following steps:

  1. Access your Snowflake account and open an empty worksheet (query editor).
  2. Run the following query and create a catalog integration with AWS Glue Data Catalog. Replace <YOUR_ACCOUNT_ID> with the IAM role ARN from the snowflake-iceberg CloudFormation Ouputs tab, and replace <REGION> with the region of AWS Glue Data Catalog.
CREATE CATALOG INTEGRATION glue_catalog_integration
  CATALOG_SOURCE=GLUE
  CATALOG_NAMESPACE='delta_uniform_db'
  TABLE_FORMAT=ICEBERG
  GLUE_AWS_ROLE_ARN='arn:aws:iam::<YOUR_ACCOUNT_ID>:role/SnowflakeIcebergGlueCatalogRole'
  GLUE_CATALOG_ID='<YOUR_ACCOUNT_ID>'
  GLUE_REGION='<REGION>'
  ENABLED=TRUE;
  1. Retrieve GLUE_AWS_IAM_USER_ARN and GLUE_AWS_EXTERNAL_ID by using DESCRIBE CATALOG INTEGRATION glue_catalog_integration in the editor. The output is similar to the following:
+------------------------------------------------------------------------------------------------------------------------------+
| property                 | property_type | property_value                                                 | property_default |
|--------------------------+---------------+----------------------------------------------------------------+------------------|
| ENABLED                  | Boolean       | true                                                           | false            |
| CATALOG_SOURCE           | String        | GLUE                                                           |                  |
| CATALOG_NAMESPACE        | String        | delta_uniform_db                                               |                  |
| TABLE_FORMAT             | String        | ICEBERG                                                        |                  |
| REFRESH_INTERVAL_SECONDS | Integer       | 30                                                             | 30               |
| GLUE_AWS_ROLE_ARN        | String        | arn:aws:iam::123456789012:role/SnowflakeIcebergGlueCatalogRole |                  |
| GLUE_CATALOG_ID          | String        | 123456789012                                                   |                  |
| GLUE_REGION              | String        | us-east-1                                                      |                  |
| GLUE_AWS_IAM_USER_ARN    | String        | arn:aws:iam::123456789012:user/<ID>                            |                  |
| GLUE_AWS_EXTERNAL_ID     | String        | An external ID specified on the IAM Role trust relationships   |                  |
| COMMENT                  | String        |                                                                |                  |
+------------------------------------------------------------------------------------------------------------------------------+
  1. Update the IAM role you created using the CloudFormation stack to enable Snowflake to access AWS Glue Data Catalog using that IAM role. Open Trust Relationships of SnowflakeIcebergGlueCatalogRole on the IAM console, choose Edit and update the trust relationship using the following policy. Replace <GLUE_AWS_IAM_USER_ARN> and <GLUE_AWS_EXTERNAL_ID> with the names you obtained in the previous step.
{
   "Version": "2012-10-17",
   "Statement": [
	  {
		 "Sid": "",
		 "Effect": "Allow",
		 "Principal": {
			"AWS": "<GLUE_AWS_IAM_USER_ARN>"
		 },
		 "Action": "sts:AssumeRole",
		 "Condition": {
			"StringEquals": {
			   "sts:ExternalId": "<GLUE_AWS_EXTERNAL_ID>"
			}
		 }
	  }
   ]
}

You completed setting up the IAM role for Snowflake to access your Data Catalog resources. Next, configure the IAM role for Amazon S3 access.

Register Amazon S3 as an external volume

In this section, you configure an external volume for Amazon S3. Snowflake accesses the UniForm table data files in S3 through the external volume. For the configuration of an external volume for S3, refer to Configure an external volume for Amazon S3 in Snowflake public documentation. To configure the external volume, complete the following steps:

  1. In the query editor, run the following query to create an external volume for the Delta Lake S3 bucket. Replace <DeltaLakeS3Bucket> with the name of the S3 bucket that you created in Launch a CloudFormation template to configure basic resources from the CloudFormation Outputs tab. Replace <ACCOUNT_ID> with your AWS account ID.
CREATE OR REPLACE EXTERNAL VOLUME delta_lake_uniform_s3
   STORAGE_LOCATIONS =
	  (
		 (
			NAME = 'delta-lake-uniform-on-aws'
			STORAGE_PROVIDER = 'S3'
			STORAGE_BASE_URL = 's3://<DeltaLakeS3Bucket>'
			STORAGE_AWS_ROLE_ARN = 'arn:aws:iam::<ACCOUNT_ID>:role/SnowflakeIcebergS3Role'
		 )
	  );
  1. Retrieve STORAGE_AWS_IAM_USER_ARN and STORAGE_AWS_EXTERNAL_ID by running DESCRIBE EXTERNAL VOLUME delta_lake_uniform_s3 in the editor. The output is similar to the following:
+------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+
| parent_property   | property           | property_type | property_value                                                                                                                       | property_default |
|-------------------+--------------------+---------------+--------------------------------------------------------------------------------------------------------------------------------------+------------------|
|                   | ALLOW_WRITES       | Boolean       | true                                                                                                                                 | true             |
| STORAGE_LOCATIONS | STORAGE_LOCATION_1 | String        | {"NAME":"uniform_s3_location","STORAGE_PROVIDER":"S3","STORAGE_BASE_URL":"s3://<DeltaLakeS3Bucket>","STORAGE_ALLOWED_LOCATIONS":["s3 |                  |
|                   |                    |               | ://<DeltaLakeS3Bucket>/*"],"STORAGE_REGION":"us-east-1","PRIVILEGES_VERIFIED":true,"STORAGE_AWS_ROLE_ARN":"arn:aws:iam::123456789012 |                  |
|                   |                    |               | :role/SnowflakeIcebergS3Role","STORAGE_AWS_IAM_USER_ARN":"arn:aws:iam::123456789012:user/<ID>","STORAGE_AWS_EXTERNAL_ID":"<External  |                  |
|                   |                    |               | ID>",... }                                                                                                                           |                  |
| STORAGE_LOCATIONS | ACTIVE             | String        | uniform_s3_location                                                                                                                  |                  |
+------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+
  1. Update the IAM role you created using the CloudFormation template (in Create IAM roles for Snowflake to access AWS Glue Data Catalog and Amazon S3) to enable Snowflake to use this IAM role. Open Trust Relationships of SnowflakeIcebergS3Role on the IAM console, choose Edit, and update the trust relationship with the following policy. Replace <STORAGE_AWS_IAM_USER_ARN> and <STORAGE_AWS_EXTERNAL_ID> with the values from the previous step.
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "",
      "Effect": "Allow",
      "Principal": {
        "AWS": "<STORAGE_AWS_IAM_USER_ARN&>"
      },
      "Action": "sts:AssumeRole",
      "Condition": {
        "StringEquals": {
          "sts:ExternalId": "<STORAGE_AWS_EXTERNAL_ID>"
        }
      }
    }
  ]
}

The next step is to create an Iceberg table to run queries from Snowflake.

Create an Iceberg table in Snowflake

In this section, you create an Iceberg table in Snowflake. The table is an entry point for Snowflake to access the Delta Lake UniForm table in AWS Glue Data Catalog. To create the table, complete the following steps:

  1. (Optional) If you don’t have a database in Snowflake, run CREATE DATABASE <DATABASE_NAME>, replacing <DATABASE_NAME> with a unique database name for the Iceberg table.
  2. Run the following query in the Snowflake query editor. In this case, the database delta_uniform_snow_db is chosen for the table. Configure the following parameters:
    1. EXTERNAL_VOLUME: created by CREATE OR REPLACE EXTERNAL VOLUME query in the previous section, such as delta_lake_uniform_s3.
    2. CATALOG: created by the CREATE CATALOG INTEGRATION query in the previous section, such as glue_catalog_integration.
    3. CATALOG_TABLE_NAME: the name of Delta Lake UniForm table you created in Data Catalog such as customer_reviews.

The complete query is below:

CREATE OR REPLACE ICEBERG TABLE customer_reviews_snow
  EXTERNAL_VOLUME='delta_lake_uniform_s3'
  CATALOG='glue_catalog_integration'
  CATALOG_TABLE_NAME='customer_reviews';

After the table creation is complete, you’re ready to query the UniForm table in AWS Glue Data Catalog from Snowflake.

Query the UniForm table from Snowflake

In this step, you query the UniForm table from Snowflake. Paste and run the following analytic query in the Snowflake query editor.

SELECT product_category, count(*) as count_by_product_category 
FROM customer_reviews_snow 
GROUP BY product_category ORDER BY count_by_product_category DESC

The query result shows the same output as you saw in Review the added records in Delta Lake UniForm table from Amazon Redshift Serverless section.

+--------------------------------------------------+
| PRODUCT_CATEGORY     | COUNT_BY_PRODUCT_CATEGORY |
|----------------------+---------------------------|
| Office_Products      | 9673711                   |
| Books                | 9672664                   |
| Apparel              | 6448747                   |
| Computers            | 3224215                   |
| Beauty_Personal_Care | 3223599                   |
+--------------------------------------------------+

Now you can query from Snowflake against the Delta Lake table by enabling Delta Lake UniForm.


About the Authors

Tomohiro Tanaka is a Senior Cloud Support Engineer at Amazon Web Services. He’s passionate about helping customers use Apache Iceberg for their data lakes on AWS. In his free time, he enjoys a coffee break with his colleagues and making coffee at home.

Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He works based in Tokyo, Japan. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his road bike.

Fine-grained access control in Amazon EMR Serverless with AWS Lake Formation

Post Syndicated from Anubhav Awasthi original https://aws.amazon.com/blogs/big-data/fine-grained-access-control-in-amazon-emr-serverless-with-aws-lake-formation/

In today’s data-driven world , enterprises are increasingly reliant on vast amounts of data to drive decision-making and innovation. With this reliance comes the critical need for robust data security and access control mechanisms. Fine-grained access control restricts access to specific data subsets, protecting sensitive information and maintaining regulatory compliance. It allows organizations to set detailed permissions at various levels, including database, table, column, and row. This precise control mitigates risks of unauthorized access, data leaks, and misuse. In the unfortunate event of a security incident, fine-grained access control helps limit the scope of the breach, minimizing potential damage.
AWS is introducing general availability of fine-grained access control based on AWS Lake Formation for Amazon EMR Serverless on Amazon EMR 7.2. Enterprises can now significantly enhance their data governance and security frameworks. This new integration supports the implementation of modern data lake architectures, such as data mesh, by providing a seamless way to manage and analyze data. You can use EMR Serverless to enforce data access controls using Lake Formation when reading data from Amazon Simple Storage Service (Amazon S3), enabling robust data processing workflows and real-time analytics without the overhead of cluster management.

In this post, we discuss how to implement fine-grained access control in EMR Serverless using Lake Formation. With this integration, organizations can achieve better scalability, flexibility, and cost-efficiency in their data operations, ultimately driving more value from their data assets.

Key use cases for fine-grained access control in analytics

The following are key use cases for fine-grained access control in analytics:

  • Customer 360 – You can enable different departments to securely access specific customer data relevant to their functions. For example, the sales team can be granted access only to data such as customer purchase history, preferences, and transaction patterns. Meanwhile, the marketing team is limited to viewing campaign interactions, customer demographics, and engagement metrics.
  • Financial reporting – You can enable financial analysts to access the necessary data for reporting and analysis while restricting sensitive financial details to authorized executives.
  • Healthcare analytics – You can enable healthcare researchers and data scientists to analyze de-identified patient data for medical advancements and research, while making sure Protected Health Information (PHI) remains confidential and accessible only to authorized healthcare professionals and personnel.
  • Supply chain optimization – You can grant logistics teams visibility into inventory and shipment data while limiting access to pricing or supplier information to relevant stakeholders.

Solution overview

In this post, we explore how to implement fine-grained access control on Iceberg tables within an EMR Serverless application, using the capabilities of Lake Formation. If you’re interested in learning how to implement fine-grained access control on open table formats in Amazon EMR running on Amazon Elastic Compute Cloud (Amazon EC2) instances using Lake Formation, refer to Enforce fine-grained access control on Open Table Formats via Amazon EMR integrated with AWS Lake Formation.
With the data access control features available in Lake Formation, you can enforce granular permissions and govern access to specific columns, rows, or cells within your Iceberg tables. This approach makes sure sensitive data remains secure and accessible only to authorized users or applications, aligning with your organization’s data governance policies and regulatory compliance requirements.

A cross-account modern data platform on AWS involves setting up a centralized data lake in a primary AWS account, while allowing controlled access to this data from secondary AWS accounts. This setup helps organizations maintain a single source of truth for their data, provides consistent data governance, and uses the robust security features of AWS across multiple business units or project teams.

To demonstrate how you can use Lake Formation to implement cross account fine-grained access control within an EMR Serverless environment, we use the TPC-DS dataset to create tables in the AWS Glue Data Catalog in the AWS producer account and provision different user personas to reflect various roles and access levels in the AWS consumer account, forming a secure and governed data lake.

The following diagram illustrates the solution architecture.

The producer account contains the following persona:

  • Data engineer – Tasks include data preparation, bulk updates, and incremental updates. The data engineer has the following access:
    • Table-level access – Full read/write access to all TPC-DS tables.

The consumer account contains the following personas:

  • Finance analyst – We run a sample query that performs a sales data analysis to guide marketing, inventory, and promotion strategies based on demographic and geographic performance. The finance analyst has the following access:
    • Table-level access – Full access to tables store_sales, catalog_sales, web_sales, item, and promotion for comprehensive financial analysis.
    • Column-level access – Limited access to cost-related columns in the sales tables to avoid exposure to sensitive pricing strategies. Limited access to sensitive columns like credit_rating in the customer_demographics table.
    • Row-level access – Access only to sales data from the current fiscal year or specific promotional periods.
  • Product analyst – We run a sample query that does a customer behavior analysis to tailor marketing, promotions, and loyalty programs based on purchase patterns and regional insights. The product analyst has the following access:
    • Table-level access – Full access to tables item, store_sales, and customer tables to evaluate product and market trends.
    • Column-level access – Restricted access to personal identifiers in the customer table, such as customer_address , email_address, and date of birth.

Prerequisites

You should have the following prerequisites:

Set up infrastructure in the producer account

We provide a CloudFormation template to deploy the data lake stack with the following resources:

  • Two S3 buckets: one for scripts and query results, and one for the data lake storage
  • An Amazon Athena workgroup
  • An EMR Serverless application
  • An AWS Glue database and tables on external public S3 buckets of TPC-DS data
  • An AWS Glue database for the data lake
  • An IAM role and polices

Set up Lake Formation for the data engineer in the producer account

Set up Lake Formation cross-account data sharing version settings:

  1. Open the Lake Formation console with the Lake Formation data lake administrator in the producer account.
  2. Under Data Catalog settings, pick Version 4 under Cross-account version settings.

To learn more about the differences between data sharing versions, refer to Updating cross-account data sharing version settings. Make sure Default permissions for newly created databases and tables is unchecked.

Register the Amazon S3 location as the data lake location

When you register an Amazon S3 location with Lake Formation, you specify an IAM role with read/write permissions on that location. After registering, when EMR Serverless requests access to this Amazon S3 location, Lake Formation will supply temporary credentials of the provided role to access the data. We already created the role LakeFormationServiceRole using the CloudFormation template. To register the Amazon S3 location as the data lake location, complete the following steps:

  1. Open the Lake Formation console with the Lake Formation data lake administrator in the producer account.
  2. In the navigation pane, choose Data lake locations under Administration.
  3. Choose Register location.
  4. For Amazon S3 path, enter s3://<DatalakeBucketName>. (Copy the bucket name from the CloudFormation stack’s Outputs tab.)
  5. For IAM role, enter LakeFormationServiceRoleDatalake.
  6. For Permission mode, select Lake Formation.
  7. Choose Register location.

Generate TPC-DS tables in the producer account

In this section, we generate TPC-DS tables in Iceberg format in the producer account.
Grant database permissions to the data engineer
First, let’s grant database permissions to the data engineer IAM role Amazon-EMR-ExecutionRole_DE that we will use with EMR Serverless. Complete the following steps:

  1. Open the Lake Formation console with the Lake Formation data lake administrator in the producer account.
  2. Choose Databases and Create database.
  3. Enter iceberg_db for Name and s3://<DatalakeBucketName> for Location.
  4. Choose Create database.
  5. In the navigation pane, choose Data lake permissions and choose Grant.
  6. In the Principles section, select IAM users and roles and choose Amazon-EMR-ExecutionRole_DE.
  7. In the LF-Tags or catalog resources section, select Named Data Catalog resources and choose tpc-source and iceberg_db for Databases.
  8. Select Super for both Database permissions and Grantable permissions and choose Grant.

Create an EMR Serverless application

Now, let’s log in to EMR Serverless using Amazon EMR Studio and complete the following steps:

  1. On the Amazon EMR console, choose EMR Serverless.
  2. Under Manage applications, choose my-emr-studio. You will be directed to the Create application page on EMR Studio. Let’s create a Lake Formation enabled EMR Serverless application
  3.  Under Application settings, provide the following information:
    1. For Name, enter a name emr-fgac-application.
    2. For Type, choose Spark.
    3. For Release version, choose emr-7.2.0.
    4. For Architecture, choose x86_64.
  4. Under Application setup options, select Use custom settings.
  5. Under Interactive endpoint, select Enable endpoint for EMR studio
  6. Under Additional configurations, for Metastore configuration, select Use AWS Glue Data Catalog as metastore, then select Use Lake Formation for fine-grained access control.
  7. Under Network connections, choose emrs-vpc for the VPC, enter any two private subnets, and enter emr-serverless-sg for Security groups.
  8. Choose Create and start application.

Create a Workspace

Complete the following steps to create an EMR Workspace:

  1. On the Amazon EMR console, choose Workspaces in the navigation pane and choose Create Workspace.
  2. Enter the Workspace name emr-fgac-workspace.
  3. Leave all other settings as default and choose Create Workspace.
  4. Choose Launch Workspace. Your browser might request to allow pop-up permissions for the first time launching the Workspace.
  5. After the Workspace is launched, in the navigation pane, choose Compute.
  6. For Compute type¸ select EMR Serverless application and enter emr-fgac-application for the application and Amazon-EMR-ExecutionRole_DE as the runtime role.
  7. Make sure the kernel attached to the Workspace is PySpark.
  8. Navigate to the File browser section and choose Upload files.
  9. Upload the file Iceberg-ingest-final_v2.ipynb.
  10. Update the data lake bucket name, AWS account ID, and AWS Region accordingly.
  11. Choose the double arrow icon to restart the kernel and rerun the notebook.


To verify that the data is generated, you can go to the AWS Glue console. Under Data Catalog, Databases, you should see TPC-DS tables ending with _iceberg for the database iceberg_db.

Share the database and TPC-DS tables to the consumer account

We now grant permissions to the consumer account, including grantable permissions. This allows the Lake Formation data lake administrator in the consumer account to control access to the data within the account.

Grant database permissions to the consumer account

Complete the following steps:

  1. Open the Lake Formation console with the Lake Formation data lake administrator in the producer account.
  2. In the navigation pane, choose Databases.
  3. Select the database iceberg_db, and on the Actions menu, under Permissions, choose Grant.
  4. In the Principles section, select External accounts and enter the consumer account.
  5. In the LF-Tags or catalog resources section, select Named Data Catalog resources and choose iceberg_db for Databases.
  6. In the Database permissions section, select Describe for both Database permissions and Grantable permissions.

This allows the data lake administrator in the consumer account to describe the database and grant describe permissions to other principals in the consumer account.

Grant table permissions to the consumer account

Repeat the preceding steps to grant table permissions to the consumer account.

Choose All tables under Tables and provide select and describe permissions for Table permissions and Grantable permissions.

Set up Lake Formation in the consumer account

For the remaining section of the post, we focus on the consumer account. Deploy the following CloudFormation stack to set up resources:

The template will create the Amazon EMR runtime role for both analyst user personas.
Log in to the AWS consumer account and accept the AWS RAM invitation first:

  1. Open the AWS RAM console with the IAM identity that has AWS RAM access.
  2. In the navigation pane, choose Resource shares under Shared with me.
  3. You should see two pending resource shares from the producer account.
  4. Accept both invitations.

You should be able to see the iceberg_db database on the Lake Formation console.

Create a resource link for the shared database

To access the database and table resources that were shared by the producer AWS account, you need to create a resource link in the consumer AWS account. A resource link is a Data Catalog object that is a link to a local or shared database or table. After you create a resource link to a database or table, you can use the resource link name wherever you would use the database or table name. In this step, you grant permission on the resource links to the job runtime roles for EMR Serverless. The runtime roles will then access the data in shared databases and underlying tables through the resource link.
To create a resource link, complete the following steps:

  1. Open the Lake Formation console with the Lake Formation data lake administrator in the consumer account.
  2. In the navigation pane, choose Databases.
  3. Select the iceberg_db database, verify that the owner account ID is the producer account, and on the Actions menu, choose Create resource links.
  4. For Resource link name, enter the name of the resource link (iceberg_db_shared).
  5. For Shared database’s region, choose the Region of the iceberg_db database.
  6. For Shared database, choose the iceberg_db database.
  7. For Shared database’s owner ID, enter the account ID of the producer account.
  8. Choose Create.

Grant permissions on the resource link to the EMR job runtime roles

Grant permissions on the resource link to Amazon-EMR-ExecutionRole_Finance and Amazon-EMR-ExecutionRole_Product using the following steps:

  1. Open the Lake Formation console with the Lake Formation data lake administrator in the consumer account.
  2. In the navigation pane, choose Databases.
  3. Select the resource link (iceberg_db_shared) and on the Actions menu, choose Grant.
  4. In the Principles section, select IAM users and roles, and choose Amazon-EMR-ExecutionRole_Finance and Amazon-EMR-ExecutionRole_Product.
  5. In the LF-Tags or catalog resources section, select Named Data Catalog resources and for Databases, choose iceberg_db_shared.
  6. In the Resource link permissions section, select Describe for Resource link permissions.

This allows the EMR Serverless job runtime roles to describe the resource link. We don’t make any selections for grantable permissions because runtime roles shouldn’t be able to grant permissions to other principles.
Choose Grant.

Grant table permissions for the finance analyst

Complete the following steps:

  1. Open the Lake Formation console with the Lake Formation data lake administrator in the consumer account.
  2. In the navigation pane, choose Databases.
  3. Select the resource link (iceberg_db_shared) and on the Actions menu, choose Grant on target.
  4. In the Principles section, select IAM users and roles, then choose Amazon-EMR-ExecutionRole_Finance.
  5. In the LF-Tags or catalog resources section, select Named Data Catalog resources and specify the following:
    1. For Databases, choose iceberg_db.
    2. For Tables¸ choose store_sales_iceberg.
  6. In the Table permissions section, for Table permissions, select Select.
  7. In the Data permissions section, select Column-based access.
  8. Select Exclude columns and choose all cost-related columns (ss_wholesale_cost and ss_ext_wholesale_cost).
  9. Choose Grant.
  10. Similarly, grant access to table customer_demographics_iceberg and exclude the column cd_credit_rating.
  11. Following the same steps, grant All data access for tables store_iceberg and item_iceberg.
  12. For the table date_dim_iceberg, we provide selective row-level access.
  13. Similar to the preceding table permissions, select date_dim_iceberg under Tables and in the Data filters section, choose Create new.
  14. For Data filter name, enter FA_Filter_year.
  15. Select Access to all columns under Column-level access.
  16. Select Filter rows and for Row filter expression, enter d_year=2002 to only provide access to the 2002 year.
  17. Choose Save changes.
  18. Choose Create filter.
  19. Make sure FA_Filter_year is selected under Data filters and grant select permissions on the filter.

Grant table permissions for the product analyst

You can provide permissions for the next set of tables required for the product analyst role using the Lake Formation console. Alternatively, you can use the AWS Command Line Interface (AWS CLI) to grant permissions. We provide grant on target permissions for the resource link iceberg_db_shared to IAM role Amazon-EMR-ExecutionRole_Product.

  1. Similar to steps followed in previous sections, for table store_sales_iceberg, date_dim_iceberg, store_iceberg, and house_hold_demographics_iceberg, provide select permissions for All data access. Make sure the role selected is Amazon-EMR-ExecutionRole_Product.

For table customer_iceberg, we limit access to personally identifiable information (PII) columns.

  1. Under Data permissions, select Column-based access and Exclude columns.
  2. Choose columns c_birth_day, c_birth_month, c_birth_year, c_current_addr_sk, c_customer_id, c_email_address, and c_birth_country.

Verify access using interactive notebooks from EMR Studio

Complete the following steps to test role access:

  1. Log in to the AWS consumer account and open the Amazon EMR console.
  2. Choose EMR Serverless in the navigation pane and choose an existing EMR Studio.
  3. If you don’t have EMR Studio configured, choose Get Started and select Create and launch EMR Studio.
  4. Create a Lake Formation enabled EMR Serverless application as described in previous sections.
  5. Create an EMR Studio Workspace as described in previous sections.
  6. Use emr-studio-service-role for Service role and datalake-resources-<account_id>-<region> for Workspace storage, then launch your Workspace.

Now, let’s verify access for the finance analyst.

  1. Make sure the compute type inside your Workspace is pointing to the EMR Serverless application created in the prior step and Amazon-EMR-ExecutionRole_Finance as the interactive runtime role.
  2. Go to File browser in the navigation pane, choose Upload files, and add Notebook_FA.ipynb to your Workspace.
  3. Run all the cells to verify fine-grained access.

Now let’s test access for the product analyst.

  1. In the same Workspace, detach and attach the same EMR Serverless application with Amazon-EMR-ExecutionRole_Product as the interactive runtime role.
  2. Upload Notebook_PA.ipynb under the File browser section.
  3. Run all the cells to verify fine-grained access for the product analyst.

In a real-world scenario, both analysts will likely have their own Workspace with restricted rights to assume only the authorized interactive runtime role.

Considerations and limitations

EMR Serverless with Lake Formation uses Spark resource profiles to create two profiles and two Spark drivers for access control. Read this white paper to learn about the feature details. The user profile runs the supplied code, and the system profile enforces Lake Formation policies. Therefore, it’s recommended that you have a minimum of two Spark drivers when pre-initialized capacity is used with Lake Formation enabled jobs. No change in executor count is required. Refer to Using EMR Serverless with AWS Lake Formation for fine-grained access control to learn more about the technical implementation of the Lake Formation integration with EMR Serverless.

You can expect a performance overhead after enabling Lake Formation. The level of access (table, column, or row) and the amount of data filtered will have significant impact on query performance.

Clean up

To avoid incurring ongoing costs, complete the following steps to clean up your resources:

  1. In your secondary (consumer)  account, log in to the Lake Formation console.
  2. Drop the resource share table.
  3. In your primary (producer) account, log in to the Lake Formation console.
  4. Revoke the access you configured.
  5. Drop the AWS Glue tables and database.
  6. Delete the AWS Glue job.
  7. Delete the S3 buckets and any other resources that you created as part of the prerequisites for this post.

Conclusion

In this post, we showed how to integrate Lake Formation with EMR Serverless to manage access to Iceberg tables. This solution showcases a modern way to enforce fine-grained access control in a multi-account open data lake setup. The approach simplifies data management in the main account while carefully controlling how users access data in other secondary accounts.

Try out the solution for your own use case, and let us know your feedback and questions in the comments section.


About the Authors

Anubhav Awasthi is a Sr. Big Data Specialist Solutions Architect at AWS. He works with customers to provide architectural guidance for running analytics solutions on Amazon EMR, Amazon Athena, AWS Glue, and AWS Lake Formation.

Nishchai JM is an Analytics Specialist Solutions Architect at Amazon Web services. He specializes in building Big-data applications and help customer to modernize their applications on Cloud. He thinks Data is new oil and spends most of his time in deriving insights out of the Data.

Analyze Amazon EMR on Amazon EC2 cluster usage with Amazon Athena and Amazon QuickSight

Post Syndicated from Boon Lee Eu original https://aws.amazon.com/blogs/big-data/analyze-amazon-emr-on-amazon-ec2-cluster-usage-with-amazon-athena-and-amazon-quicksight/

Gaining granular visibility into application-level costs on Amazon EMR on Amazon Elastic Compute Cloud (Amazon EC2) clusters presents an opportunity for customers looking for ways to further optimize resource utilization and implement fair cost allocation and chargeback models. By breaking down the usage of individual applications running in your EMR cluster, you can unlock several benefits:

  • Informed workload management – Application-level cost insights empower organizations to prioritize and schedule workloads effectively. Resource allocation decisions can be made with a better understanding of cost implications, potentially improving overall cluster performance and cost-efficiency.
  • Cost optimization – With granular cost attribution, organizations can identify cost-saving opportunities for individual applications. They can right-size underutilized resources or prioritize optimization efforts for applications that are driving high usage and costs.
  • Transparent billing – In multi-tenant environments, organizations can implement fair and transparent cost allocation models based on individual application resource consumption and associated costs. This fosters accountability and enables accurate chargebacks to tenants.

In this post, we guide you through deploying a comprehensive solution in your Amazon Web Services (AWS) environment to analyze Amazon EMR on EC2 cluster usage. By using this solution, you will gain a deep understanding of resource consumption and associated costs of individual applications running on your EMR cluster. This will help you optimize costs, implement fair billing practices, and make informed decisions about workload management, ultimately enhancing the overall efficiency and cost-effectiveness of your Amazon EMR environment. This solution has been only tested on Spark workloads running on EMR on EC2 that uses YARN as its resource manager. It hasn’t been tested on workloads from other frameworks that run on YARN, such as HIVE or TEZ.

Solution overview

The solution works by running a Python script on the EMR cluster’s primary node to collect metrics from the YARN resource manager and correlate them with cost usage details from the AWS Cost and Usage Reports (AWS CUR). The script activated by a cronjob makes HTTP requests to the YARN resource manager to collect two types of metrics from paths /ws/v1/cluster/metrics for cluster metrics and /ws/v1/cluster/apps for application metrics. The cluster metrics contain utilization information of cluster resources, and the application metrics contain utilization information of an application or job. These metrics are stored in an Amazon Simple Storage Service (Amazon S3) bucket.

There are two YARN metrics that capture the resource utilization information of an application or job.

  • memorySeconds – This is the memory (in MB) allocated to an application times the number of seconds the application ran
  • vcoreSeconds – This is the number of YARN vcores allocated to an application times the number of seconds application ran

The solution uses memorySeconds to derive the cost of running the application or job. It can be modified to use vcoreSeconds instead if necessary.

The metadata of the YARN metrics collected in Amazon S3 is created, stored, and represented as database and tables in AWS Glue Data Catalog, which is in turn available to Amazon Athena for further processing. You can now write SQL queries in Athena to correlate the YARN metrics with the cost usage information from AWS CUR to derive the detailed cost breakdown of your EMR cluster by infrastructure and application. This solution creates two corresponding Athena views of the respective cost breakdown that will become the data source to Amazon QuickSight for visualization.

The following diagram shows the solution architecture.

EMR Cluster Usage Utility Solution Architecture

Prerequisites

To perform the solution, you need the following prerequisites:

  1. Confirm that a CUR is created in your AWS account. It needs an S3 bucket to store the report files. Follow the steps described in Creating Cost and Usage Reports to create the CUR on the AWS Management Console. When creating the report, make sure the following settings are enabled:
    • Include resource IDs
    • Time granularity is set to hourly
    • Report data integration to Athena

It can take up to 24 hours for AWS to start delivering reports to your S3 bucket. Thereafter, your CUR gets updated at least one time a day.

  1. The solution needs Athena to run queries against the data from the CUR using standard SQL. To automate and streamline the integration of Athena with CUR, AWS provides an AWS CloudFormation template, crawler-cfn.yml, which is automatically generated in the same S3 bucket during CUR creation. Follow the instructions in Setting up Athena using AWS CloudFormation templates to integrate Athena with the CUR. This template will create an AWS Glue database that references to the CUR, an AWS Lambda event and an AWS Glue crawler that gets invoked by S3 event notification to update the AWS Glue database whenever the CUR gets updated.
  2. Make sure to activate the AWS generated cost allocation tag, aws:elasticmapreduce:job-flow-id. This enables the field, resource_tags_aws_elasticmapreduce_job_flow_id, in the CUR to be populated with the EMR cluster ID and is used by the SQL queries in the solution. To activate the cost allocation tag from the management console, follow these steps:
    • Sign in to the payer account’s AWS Management Console and open the AWS Billing and Cost Management console
    • In the navigation pane, choose Cost Allocation Tags
    • Under AWS generated cost allocation tags, choose the aws:elasticmapreduce:job-flow-id tag
    • Choose Activate. It can take up to 24 hours for tags to activate.

The following screenshot shows an example of the aws:elasticmapreduce:job-flow-id tag being activated.

CostAllocationTag

You can now test out this solution on an EMR cluster in a lab environment. If you’re not already familiar with EMR, follow the detailed instructions provided in Tutorial: Getting started with Amazon EMR to launch a new EMR cluster and run a sample Spark job.

Deploying the solution

To deploy the solution, follow the steps in the next sections.

Installing scripts to the EMR cluster

Download two scripts from the GitHub repository and save them into an S3 bucket:

  • emr_usage_report.py – Python script that makes the HTTP requests to YARN Resource Manager
  • emr_install_report.sh  – Bash script that creates a cronjob to run the python script every minute

To install the scripts, add a step to the EMR cluster through the console or AWS Command Line Interface (AWS CLI) using aws emr add-step command.

Replace:

  • REGION with the AWS Regions where the cluster is running (for example, Europe (Ireland) eu-west-1)
  • MY-BUCKET with the name of the bucket where the script is stored (for example, my.artifact.bucket)
  • MY_REPORT_BUCKET with the bucket name where you want to collect YARN metrics (for example, my.report.bucket)
aws emr add-steps \
--cluster-id j-XXXXXXXXXXXXX \
--steps Type=CUSTOM_JAR,Name="Install YARN reporter",Jar=s3://REGION.elasticmapreduce/libs/script-runner/script-runner.jar,Args=[s3://<MY-BUCKET>/emr-install_reporter.sh,s3://<MY-BUCKET>/emr_usage_reporter.py,MY_REPORT_BUCKET]

You can now run some Spark jobs on your EMR cluster to start generating application usage metrics.

Launching the CloudFormation stack

When the prerequisites are met and you have the scripts deployed so that your EMR clusters are sending YARN metrics to an S3 bucket, the rest of the solution can be deployed using CloudFormation.

Before launching the stack, upload a copy of this QuickSight definition file into an S3 bucket required by the CloudFormation template to build the initial analysis in QuickSight. When ready, proceed to launch your stack to provision the remaining resources of the solution.

  1. Choose

This automatically launches AWS CloudFormation in your AWS account with a template. It prompts you to sign in as needed and make sure you create the stack in your intended Region.

The CloudFormation stack requires a few parameters, as shown in the following screenshot.

CloudFormationStack

The following table describes the parameters.

Parameter Description
Stack name A meaningful name for the stack; for example, EMRUsageReport
S3 configuration
YARNS3BucketName Name of S3 bucket where YARN metrics are stored
Cost Usage Report configuration
CURDatabaseName Name of Cost Usage Report database in AWS Glue
CURTableName Name of Cost Usage Report table in AWS Glue
AWS Glue Database configuration
EMRUsageDBName Name of AWS Glue database to be created for the EMR Cost Usage Report
EMRInfraTableName Name of AWS Glue table to be created for infrastructure usage metrics
EMRAppTableName Name of AWS Glue table to be created for application usage metrics
QuickSight configuration
QSUserName Name of QuickSight user in default namespace to manage the EMR Usage Report resources in QuickSight.
QSDefinitionsFile S3 URI of the definition JSON file for the EMR Usage Report.
  1. Enter the parameter values from the preceding table.
  2. Choose Next.
  3. On the next screen, enter any necessary tags, an AWS Identity and Access Management (IAM) role, stack failure, or advanced options if necessary. Otherwise, you can leave them as default.
  4. Choose Next.
  5. Review the details on the final screen and select the check boxes confirming AWS CloudFormation might create IAM resources with custom names or require CAPABILITY_AUTO_EXPAND.
    CloudFormationCheckbox
  6. Choose Create.

The stack will take a couple of minutes to create the remaining resources for the solution. After the CloudFormation stack is created, on the Outputs tab, you can find the details of the resources created.

Reviewing the correlation results

The CloudFormation template creates two Athena views containing the correlated cost breakdown details of the YARN cluster and application metrics with the CUR. The CUR aggregates cost hourly and therefore correlation to derive the cost of running an application is prorated based on the hourly running cost of the EMR cluster.

The following screenshot shows the Athena view for the correlated cost breakdown details of YARN cluster metrics.

CorrelationResults

The following table describes the fields in the Athena view for YARN cluster metrics.

Field Type Description
cluster_id string ID of the cluster.
family string Resource type of the cluster. Possible values are compute instance, elastic map reduce instance, storage and data transfer.
billing_start timestamp Start billing hour of the resource.
usage_type string A specific type or unit of the resource such as BoxUsage:m5.xlarge of compute instance.
cost string Cost associated with the resource.

The following screenshot shows the Athena view for the correlated cost breakdown details of YARN application metrics.

CostBreakdownYARNAppMetrics

The following table describes the fields in the Athena view for YARN application metrics.

Field Type Description
cluster_id string ID of the cluster
id string Unique identifier of the application run
user string User name
name string Name of the application
queue string Queue name from YARN resource manager
finalstatus string Final status of application
applicationtype string Type of the application
startedtime timestamp Start time of the application
finishedtime timestamp End time of the application
elapsed_sec double Time taken to run the application
memoryseconds bigint The memory (in MB) allocated to an application times the number of seconds the application ran
vcoreseconds int The number of YARN vcores allocated to an application times the number of seconds application ran
total_memory_mb_avg double Total amount of memory (in MB) available to the cluster in the hour
memory_sec_cost double Derived unit cost of memoryseconds
application_cost double Derived cost associated with the application based on memoryseconds
total_cost double Total cost of resources associated with the cluster for the hour

Building your own visualization

In QuickSight, the CloudFormation template creates two datasets that reference Athena views as data sources and a sample analysis. The sample analysis has two sheets, EMR Infra Spend and EMR App Spend. They have a prepopulated bar chart and pivot tables to demonstrate how you can use the datasets to build your own visualization to present the cost breakdown details of your EMR clusters.

EMR Infra Spend sheet references to the YARN cluster metrics dataset. There is a filter for date range selection and a filter for cluster ID selection. The sample bar chart shows the consolidated cost breakdown of the resources for each cluster during the period. The pivot table breaks them down further to show their daily expenditure.

The following screenshot shows the EMR Infra Spend sheet from sample analysis created by the CloudFormation template.

EMR App Spend sheet references to the YARN application metrics. There is a filter for date range selection and a filter for cluster ID selection. The pivot table in this sheet shows how you can use the fields in the dataset to present the cost breakdown details of the cluster by users to observe the applications that were run, whether they were completed successfully or not, the time and duration of each run, and the derived cost of the run.

The following screenshot shows the EMR App Spend sheet from sample analysis created by the CloudFormation template.

Cleanup

If you no longer need the resources you created during this walkthrough, delete them to prevent incurring additional charges. To clean up your resources, complete the following steps:

  1. On the CloudFormation console, delete the stack that you created using the template
  2. Terminate the EMR cluster
  3. Empty or delete the S3 bucket used for YARN metrics

Conclusion

In this post, we discussed how to implement a comprehensive cluster usage reporting solution that provides granular visibility into the resource consumption and associated costs of individual applications running on your Amazon EMR on EC2 cluster. By using the power of Athena and QuickSight to correlate YARN metrics with cost usage details from your Cost and Usage Report, this solution empowers organizations to make informed decisions. With these insights, you can optimize resource allocation, implement fair and transparent billing models based on actual application usage, and ultimately achieve greater cost-efficiency in your EMR environments. This solution will help you unlock the full potential of your EMR cluster, driving continuous improvement in your data processing and analytics workflows while maximizing return on investment.


About the authors

Boon Lee Eu is a Senior Technical Account Manager at Amazon Web Services (AWS). He works closely and proactively with Enterprise Support customers to provide advocacy and strategic technical guidance to help plan and achieve operational excellence in AWS environment based on best practices. Based in Singapore, Boon Lee has over 20 years of experience in IT & Telecom industries.

Kyara Labrador is a Sr. Analytics Specialist Solutions Architect at Amazon Web Services (AWS) Philippines, specializing in big data and analytics. She helps customers in designing and implementing scalable, secure, and cost-effective data solutions, as well as migrating and modernizing their big data and analytics workloads to AWS. She is passionate about empowering organizations to unlock the full potential of their data.

Vikas Omer is the Head of Data & AI Solution Architecture for ASEAN at Amazon Web Services (AWS). With over 15 years of experience in the data and AI space, he is a seasoned leader who leverages his expertise to drive innovation and expansion in the region. Vikas is passionate about helping customers and partners succeed in their digital transformation journeys, focusing on cloud-based solutions and emerging technologies.

Lorenzo Ripani is a Big Data Solution Architect at AWS. He is passionate about distributed systems, open source technologies and security. He spends most of his time working with customers around the world to design, evaluate and optimize scalable and secure data pipelines with Amazon EMR.

Apache HBase online migration to Amazon EMR

Post Syndicated from Dalei Xu original https://aws.amazon.com/blogs/big-data/apache-hbase-online-migration-to-amazon-emr/

Apache HBase is an open source, non-relational distributed database developed as part of the Apache Software Foundation’s Hadoop project. HBase can run on Hadoop Distributed File System (HDFS) or Amazon Simple Storage Service (Amazon S3), and can host very large tables with billions of rows and millions of columns.

The followings are some typical use cases for HBase:

  • In an ecommerce scenario, when retrieving detailed product information based on the product ID, HBase can provide a quick and random query function.
  • In security assessment and fraud detection cases, the evaluation dimensions for users vary. HBase’s non-relational architectural design and ability to freely scale columns help cater to the complex needs.
  • In a high-frequency, real-time trading platform, HBase can support highly concurrent reads and writes, resulting in higher productivity and business agility.

Recommended HBase deployment mode

Starting with Amazon EMR 5.2.0, you have the option to run Apache HBase on Amazon S3.

Running HBase on Amazon S3 has several added benefits, including lower costs, data durability, and easier scalability. And during HBase migration, you can export the snapshot files to S3 and use them for recovery.

Recommended HBase migration mode

For existing HBase clusters (including self-built based on open source HBase or provided by vendors or other cloud service providers), we recommend using HBase snapshot and replication technologies to migrate to Apache HBase on Amazon EMR without significant downtime of service.

This blog post introduces a set of typical HBase migration solutions with best practices based on real-world customers’ migration case studies. Additionally, we deep dive into some key challenges faced during migrations, such as:

  • Using HBase snapshots to implement initial migration and HBase replication for real-time data migration.
  • HBase provided by other cloud platforms doesn’t support snapshots.
  • A single table with large amounts of data, for example more than 50 TB.
  • Using BucketCache to improve read performance after migration.

HBase snapshots allow you to take a snapshot of a table without too much impact on region servers, snapshots, clones, and restore operations don’t involve data copying. Also, exporting a snapshot to another cluster has little impact on the region servers.

HBase replication is a way to copy data between HBase clusters. It allows you to keep one cluster’s state synchronized with that of another cluster, using the write-ahead log (WAL) of the source cluster to propagate changes. It can work as a disaster recovery solution and also provides higher availability in the architecture.

Prerequisites

To implement HBase migration, you must have the following prerequisites:

Solution summary

In this example, we walk through a typical migration solution, which is from the source HBase on HDFS cluster (Cluster A) to the target Amazon EMR HBase on S3 (Cluster B). The following diagram illustrates the solution architecture.

Solution architecture

To demonstrate the best practice recommended to the HBase migration process, the following are the detailed steps we will walk through, as shown in the preceding diagram.

Step Activity Description Estimated time
1

Configure cluster A

(Source HBase)

Modify the configuration of the source HBase cluster to prepare for subsequent snapshot exports Less than 5 minutes
2

Create cluster B

(Amazon EMR HBase on S3)

Create an EMR cluster with HBase on Amazon S3 as the migration target cluster Less than 10 minutes
3 Configure replication Configure replication from the source HBase cluster to Amazon EMR HBase, but do not start Less than 1 minute
4 Pause service Pause the service of the source HBase cluster Less than 1 minute
5 Create snapshot Create a snapshot for each table on the source HBase cluster Less than 5 minutes
6 Resume service Resume the service of the source HBase cluster Less than 1 minute
7 Snapshot export and restore Use snapshot to migrate data from the source HBase cluster to the Amazon EMR HBase cluster Depends on the size of the table data volume
8 Start replication Start the replication of the source HBase cluster to Amazon EMR HBase and synchronize incremental data Depends on the size of the data accumulated during the snapshot export restore.
9 Test and verify Test the and verify the Amazon EMR HBase

Solution walkthrough

In the preceding diagram and table, we have listed the operational steps of the solution. Next, we will elaborate the specific operations for each step shown in the preceding table.

1. Configure cluster A (source HBase)

When exporting a snapshot from the source HBase cluster to the Amazon EMR HBase cluster, you must modify the following settings on the source cluster to ensure the performance and stability of data transmission.

Configuration classification Configuration item Suggested value Comment
core-site fs.s3.awsAccessKeyId Your AWS access key ID The snapshot export takes a relatively long time. Without an access key and secret key, the snapshot export to Amazon S3 will encounter errors such as com.amazon.aws.emr.hadoop.fs.shaded.com. amazonaws.SdkClientException: Unable to load AWS credentials from any provider in the chain.
core-site fs.s3.awsSecretAccessKey Your AWS secret access key
yarn-site yarn.nodemanager.resource.memory-mb Half of a single core node RAM The amount of physical memory, in MB, that can be allocated for containers.
yarn-site yarn.scheduler.maximum-allocation-mb Half of a single core node RAM The maximum allocation for every container request at the ResourceManager in MB. Because snapshot export runs in the YARN Map Reduce task, it’s necessary to allocate sufficient memory to YARN to ensure transmission speed.

These values are set depending on the cluster resource, workload, and table data volume. The modification can be done using a web UI if available or by suing a standard configuration XML file. Restart the HBase service after the change is complete.

2. Create cluster B (EMR HBase on S3)

Use the following recommend settings to launch an EMR cluster:

Configuration classification Configuration item Suggested value Comment
yarn-site yarn.nodemanager.resource.memory-mb 20% of a single core node RAM Amount of physical memory, in MB, that can be allocated for containers.
yarn-site yarn.scheduler.maximum-allocation-mb 20% of a single core node RAM The maximum allocation for every container request at the ResourceManager in MB. Because snapshot restore runs in the HBase, it’s necessary to allocate a small amount of small memory to YARN and leave sufficient memory to HBase to ensure restore.
hbase-env.export HBASE_MASTER_OPTS 70% of a single core node RAM Set the Java heap size for the primary HBase.
hbase-env.export HBASE_REGIONSERVER_OPTS 70% of a single core node RAM Set the Java heap size for the HBase region server.
hbase hbase.emr.storageMode S3 Indicates that HBase uses S3 to store data.
hbase-site hbase.rootdir <Your-HBase-Folder-on-S3> Your HBase data folder on S3.

See Configure HBase for more details. Additionally, the default YARN configuration on Amazon EMR for each Amazon EC2 instance type can be found in Task configuration.

The configuration of our example is as shown in the following figure.

Instance group configurations

3. Config replication

Next, we configure the replication peer from the source HBase to the EMR cluster.

The operations include:

  • Create a peer.
  • Because the snapshot migration hasn’t been done, we start by disabling the peer.
  • Specify the table that requires replication for the peer.
  • Enable table replication.

Let’s use the table usertable as an example. The shell script is as follows:

MASTER_IP="<Master-IP>"
TABLE_NAME="usertable"
cat << EOF | sudo -u hbase hbase shell 2>/dev/null
add_peer 'PEER_$TABLE_NAME', CLUSTER_KEY => '$MASTER_IP:2181:/hbase'
disable_peer 'PEER_$TABLE_NAME'
enable_table_replication '$TABLE_NAME'
EOF

The result will like the following text.

hbase:001:0> add_peer 'PEER_usertable', CLUSTER_KEY => '<Master-IP>:2181:/hbase'
Took 13.4117 seconds 
hbase:002:0> disable_peer 'PEER_usertable'
Took 8.1317 seconds 
hbase:003:0> enable_table_replication 'usertable'
The replication of table 'usertable' successfully enabled
Took 168.7254 seconds

In this experiment, we’re using the table usertable as an example. If we have many tables that need to be configured for replication, we can use the following code:

MASTER_IP="<Master-IP>"

# Get all tables
TABLE_LIST=$(echo 'list' | sudo -u hbase hbase shell 2>/dev/null | sed -e '1,/TABLE/d' -e '/seconds/,$d' -e '/row/,$d')
# Iterate each table
for TABLE_NAME in $TABLE_LIST; do
# Add the operation
cat << EOF | sudo -u hbase hbase shell 2>/dev/null
add_peer 'PEER_$TABLE_NAME', CLUSTER_KEY => '$MASTER_IP:2181:/hbase'
disable_peer 'PEER_$TABLE_NAME'
enable_table_replication '$TABLE_NAME'
EOF
done

In the scripts of following steps, if you need to apply the operations for all tables, you can refer to the preceding code sample.

At this point, the status of the peer is Disabled, so replication won’t be started. And the data that needs to be synchronized from the source to the target EMR cluster will be backlogged at the source HBase cluster and won’t be synchronized to HBase on the EMR cluster.

After the snapshot restore (step 7) is completed on the HBase on Amazon EMR cluster, we can enable the peer to start synchronizing data.

If the source HBase version is 1.x, you must run the set_peer_tableCFs function. See HBase Cluster Replication.

4. Pause the service

To pause the service of the source HBase cluster, disable the HBase tables. You can use the following script:

sudo -u hbase bash /usr/lib/hbase/bin/disable_all_tables.sh 2>/dev/null

The result is shown in the following figure.

Disable all tables

After disabling all tables, observe the HBase UI to ensure that no background tasks are being run, and then stop any services accessing the source HBase. This will take 5-10 minutes.

The HBase UI is as shown in the following figure.

Check background tasks

5. Create a snapshot

Make sure the tables in the source HBase are disabled. Then, you can create a snapshot of the source. This process will take 1-5 minutes.

Let’s use the table usertable as an example. The shell script is as follows:

DATE=`date +"%Y%m%d"`
TABLE_NAME="usertable"
sudo -u hbase hbase snapshot create -n "${TABLE_NAME/:/_}-$DATE" -t ${TABLE_NAME} 2>/dev/null

You can check the snapshot with a script:

sudo -u hbase hbase snapshot info -list-snapshots 2>/dev/null

And the result is as shown in the following figure.

Create snapshot

6. Resume service

After the snapshot is successfully created on the source HBase, you can enable the tables and resume the services that access the source HBase. These operations take several minutes, so the total data unavailability time on the source HBase during the implementation (steps 3 to step 6) will be approximately 10 minutes.

The command to enable the table is as follows:

TABLE_NAME="usertable"
echo -e "enable '$TABLE_NAME'" | sudo -u hbase hbase shell 2>/dev/null

The result is shown in the following figure.

Enable table

At this point, you can write data to the source HBase, because the status of the replication peer is disabled, so the incremental data won’t be synchronized to the target cluster.

7. Snapshot export and restore

After the snapshot created in the source HBase, it’s time to export the snapshot to the HBase data directory on the target EMR cluster. The example script is as follows:

DATE=`date +"%Y%m%d"`
TABLE_NAME="usertable"
TARGET_BUCKET="<Your-HBase-Folder-on-S3>"
nohup sudo -u hbase hbase snapshot export -snapshot ${TABLE_NAME/:/_}-$DATE -copy-to $TARGET_BUCKET &> ${TABLE_NAME/:/_}-$DATE-export.log &

Exporting the snapshot will take from 10 minute to several hours to complete, depending on the amount of data to be exported. So we run it in the background. You can check the progress by using the yarn application -list command, as shown in the following figure.

Exporting snapshot process

As an example, if you’re using an HBase cluster with 20 r6g.4xlarge core nodes, it will take about 3 hours for 50 TB of data to be exported to Amazon S3 in same AWS Region.

After the snapshot export is completed at the source HBase, you can check the snapshot in the target EMR cluster using the following script:

sudo -u hbase hbase snapshot info -list-snapshots 2>/dev/null

The result is shown in the following figure.

Check snapshot

Confirm the snapshot name—for example, usertable-20240710 and run snapshot restore on the target EMR cluster using the following script.

TABLE_NAME="usertable"
SNAPSHOT_NAME="usertable-20240710"
cat << EOF | nohup sudo -u hbase hbase shell &> restore-snapshot.out &
disable '$TABLE_NAME'
restore_snapshot '$SNAPSHOT_NAME'
enable '$TABLE_NAME'
EOF

The snapshot restore will take from 10 minute to several hours to complete, depending on the amount of data to be restored, so we run it in the background. The result is as shown in the following figure.

Restore snapshot

You can check the progress of the restore through The Amazon EMR web interface for HBase, as shown in the following figure.

Check snapshot restore

From the Amazon EMR web interface for HBase, you can found it takes about 2 hours to run Clone Snapshot for a sample table with 50 TB of data, and then 1 additional hour to run . After these two stages, the snapshot restore is completed.

8. Start replication

After the snapshot restore is completed on the EMR cluster and the status of the table is set to enabled, you can enable HBase replication in the source HBase. The incremental data will be synchronized to the target EMR cluster.

In the source HBase, the example script is as follows:

TABLE_NAME="usertable"
echo -e "enable_peer 'PEER_$TABLE_NAME'" | sudo -u hbase hbase shell 2>/dev/null

The result is as shown in the following figure.

Enable peer

Wait for the incremental data to be synchronized from the source HBase to the HBase on EMR cluster. The time taken depends on the amount of data accumulated in the source HBase during the snapshot export and restore. In our example, it took about 10 minutes to complete the data synchronization.

You can check the replication status with scripts:

echo -e "status 'replication'" | sudo -u hbase hbase shell 2>/dev/null

The result is shown in the following figure.

Replication status

9. Test and verify

After incremental data synchronization is complete, you can start testing and verifying the results. You can use the same HBase API to access both the source and the target HBase clusters and compare the results.

To guarantee the data integrity, you can check the number of HBase table region and store files for the replicated tables from the Amazon EMR web interface for HBase, as shown in the following figure.

Check hbase region and store files

For small tables, we recommend using the HBase command to verify the number of records. After signing in to the primary node of the Amazon EMR using SSH, you can run the following command:

sudo -u hbase hbase org.apache.hadoop.hbase.mapreduce.RowCounter 'usertable'

Then, in the hbase.log file of the HBase log directory, find the number of records for the table usertable.

For large tables, you can use the HBase Java API to validate the row count in a range of row keys.

We provided sample Java code to implement this functionality. For example, we imported the demo data to usertable using the following script:

java -classpath hbase-utils-1.0-SNAPSHOT-jar-with-dependencies.jar HBaseAccess <Your-Zookeeper-IP> put 1000 20

The result is shown in the following figure.

Put demo data into HBase table

You can run the script multiple times to import enough demo data into the table, then you can use the following script to count the number of records where the value of Row Key is between user1000 and user5000, and the value of the column family:field0 is value0

java -classpath hbase-utils-1.0-SNAPSHOT-jar-with-dependencies.jar HBaseRowCounter <Your-Zookeeper-IP> usertable "user1000" "user1100" "family:field0" "value0"

The result is shown in the following figure.

HBase table row counter

You can run the same code on both the source HBase and the target Amazon EMR HBase to verify that the results are consistent. See complete code.

After these steps are complete, you can switch from the source HBase to the target Amazon EMR Hbase, completing the migration.

Clean up

After you’re done with the solution walkthrough, complete the following steps to clean up your resources:

  1. Stop the Amazon EMR on EC2 cluster.
  2. Delete the S3 bucket that stores the HBase data.
  3. Stop the source HBase cluster, and release its related resource, for example, the Amazon EC2 cluster or resources provided by other vendors or cloud service providers.

Key challenges in HBase migration

In the previous sections, we have detailed the steps to implement HBase online migration through snapshots and replication for general scenario. Many customers’ scenarios may have some differences from the general scenario, and you need to make some modifications to the process steps in order to accomplish the migration.

HBase in the cloud doesn’t support snapshot

Many cloud providers have made modifications to the open source version of HBase, resulting in these versions of HBase not providing snapshot and replication functions. However, these cloud providers will provide data transfer tools for HBase, such as Lindorm Tunnel Service, that can be used to transfer HBase data to an HBase cluster with data on HDFS.

To deploy HBase on Amazon S3, you should follow the previous migration process as the best practice, using snapshot and replication techniques to migrate to an Amazon EMR environment. To solve the problem of HBase versions that don’t support snapshots and replication, you can create an HBase on HDFS as a jump or relay cluster, which can be used to synchronize the data from a source HBase to an HDFS-based HBase cluster, then migrate from the middle cluster to the target HBase on S3.

The following diagram illustrates the solution architecture.

Solution architecture for HBase in the cloud doesn’t support snapshot

You need to add three more steps in addition to the migration steps described previously.

Step Activity Description Estimated time
1

Create Cluster B

(EMR HBase on HDFS)

Create an EMR cluster with HBase on HDFS as the relay cluster. Less than 10 minutes
2 Configure data transfer Configure the data transfer from the outer HBase cluster to Amazon EMR HBase on HDFS and start the data transfer. Less than 5 minutes
3

HBase migration

(snapshot and replication)

Treat the outer HBase cluster as an application which writes data into the Amazon EMR HBase cluster, then you can use the steps in the previous scenario to complete the migration to Amazon EMR HBase on Amazon S3.

Single table with large amounts of data

During the migration process, if the amount of data in a single table in the source HBase (Cluster A) is too large—such as 10 TB or even 50TB—you must modify the target Amazon EMR HBase cluster (Cluster B) configuration to ensure that there are no interruptions during the migration process, especially during the snapshot restore on the Amazon EMR HBase cluster. After the snapshot restore is complete, you can rebuild the Amazon EMR HBase cluster (Cluster C).

The following diagram illustrates the solution architecture for handling a very large table.

Solution architecture for handling a very large table

The following are the steps.

Step Activity Description Estimated time
1 Create Cluster B (EMR HBase on S3 for restore) Create an EMR cluster with the required configuration for a large table snapshot restore. Less than 10 minutes
2

HBase migration

(snapshot and replication)

Consider the Amazon EMR HBase on Amazon S3 as the target cluster, then you can use the steps in the first scenario to complete the migration from the source HBase to the Amazon EMR HBase on S3.
3

Recreate Cluster C

(EMR HBase on S3 for production)

After the migration is complete, Cluster B needs to be changed back to its previous configuration before migration. If it’s inconvenient to modify the parameters, you can use the previous configuration to recreate the EMR cluster (Cluster C). Less than 15 minutes
4 Rebuild replication After recreating the EMR cluster, if replication is still needed to synchronize the data, the replication from the source HBase cluster to the new EMR HBase cluster must be rebuilt. Before building the new EMR cluster, the write service on the source HBase cluster should be paused to avoid data loss on the Amazon EMR HBase. Less than 1 minute

In Step 1, create cluster B (EMR HBase on S3 for restore), use the following configuration for snapshot restore. All time values are in milliseconds.

Configuration classification Configuration item Default value Suggested value Explanation
emrfs-site fs.s3.maxConnections 1000 50000 The number of concurrent Amazon S3 connections that your applications need. The default value is 1000 and must be increased to avoid errors such as com. amazon. ws. emr. hadoop. fs. shaded. com. amazonaws. SdkClientException: Unable to execute HTTP request: timeout waiting for connection from pool.
hbase-site hbase.client.operation.timeout 300000 18000000 Operation timeout is a top-level restriction that makes sure a blocking operation in a table will not be blocked for longer than the timeout.
hbase-site hbase.master.cleaner.interval 60000 18000000 The default is to run HBase Clearer in 60,000 milliseconds, which will clear some files in the archive, resulting in an error that HFile cannot be found.
hbase-site hbase.rpc.timeout 60000 18000000 This property limits how long a single RPC call can run before timing out.
hbase-site hbase.snapshot.master.timeout.millis 300000 18000000 Timeout for the primary HBase for the snapshot procedure.
hbase-site hbase.snapshot.region.timeout 300000 18000000 Timeout for region servers to keep threads in a snapshot request pool waiting.
hbase-site hbase.hregion.majorcompaction 604800000 0

Default is 604,800,000 ms (1 week). Set to 0 to disable automatic triggering of compaction. Note that because of the change to manual triggering, you must make compaction one of the daily operation and maintenance tasks, and run it during periods of low activity to avoid impacting production. The following is the compaction script:

echo -e "major_compact '$TABLE_NAME'" | sudo -u hbase hbase shell

Adjust the suggested values based on the amount of table data, which requires conducting some experiments to determine the values to be used in the final migration plan.

Before you recreate a new EMR cluster in the production environment, disable the HBase table on the active EMR cluster. The command line is as follows:

sudo -u hbase bash /usr/lib/hbase/bin/disable_all_tables.sh 2>/dev/null
echo -e "flush 'hbase:meta'" | sudo -u hbase hbase shell 2>/dev/null

Wait for the command to execute successfully and terminate the current EMR cluster (Cluster B). Now the HBase data is kept in Amazon S3; create a new EMR cluster (Cluster C) with the previous configuration before migration, and specify HBase date folder on S3 to be the same as Cluster B.

Using Bucket Cache to improve read performance

To enhance HBase’s read performance, one of most effective method involves caching data. HBase uses BlockCache to implement caching mechanisms for the region server. Currently, HBase provides two different BlockCache implementations to cache data read from HDFS: the default on-heap LruBlockCache and the BucketCache, which is usually off-heap. Bucket cache is the most used method.

BucketCache can be deployed in offheap, file, or mmaped file mode. These three working modes are the same in terms of memory logical organization and caching process; however, the final storage media corresponding to these three working modes are different, that is, the IOEngine is different.

We recommend that customers use BucketCache in file mode, because the default storage type of Amazon Elastic Block Store (Amazon EBS) in Amazon EMR is SSD. You can put all hot data into BucketCache, which is on Amazon EBS. You can then determine the file size used by BucketCache based on the volume of hot data.

The following are the HBase configurations for BucketCache.

Configuration classification Configuration item Suggested value Explanation
emrfs-site hbase.bucketcache.ioengine files:/mnt1/hbase/cache_01.data Where to store the contents of the bucket cache. You can use offheap, file, files, mmap, or pmem. If a file or files, set it to files. Note that some earlier Amazon EMR versions can only support using one file per core node.
hbase-site hbase.bucketcache.persistent.path file:/mnt1/hbase/cache.meta The path to store the metadata of the bucket cache, used to recover the cache during startup.
hbase-site hbase.bucketcache.size Depends on the hot data volume be cached The capacity in MBs of BucketCache for each core node. If you use multiple cache files, then this size is the sum of the capacities of multiple files.
hbase-site hbase.rs.prefetchblocksonopen TRUE Whether the server should asynchronously load all the blocks when a store file is opened (data, metadata, and index). Note that enabling this property contributes to the time the region server takes to open a region and therefore initialize.
hbase-site hbase.rs.cacheblocksonwrite TRUE Whether an HFile block should be added to the block cache when the block is finished.
hbase-site hbase.rs.cachecompactedblocksonwrite TRUE Whether to cache compressed blocks during writing.

More configuration instructions for BucketCache would refer to Configuration properties.

We provided sample Java code to test HBase read performance. In the Java code, we use the putDemoData method to write test data to the table usertable, ensuring that the data is evenly distributed across HBase table regions, and then use the getDemoData method to read the data.

We tested three scenarios: HBase data stored on HDFS, on Amazon S3 without using BucketCache, and on S3 using BucketCache. To ensure that the written data isn’t cached in the first two scenarios, the cache can be cleared by restarting the the region servers.

We tested on the EMR HBase cluster, which has 10 r6g. 2xlarge core nodes. The command is as follows:

java -classpath hbase-utils-1.0-SNAPSHOT-jar-with-dependencies.jar HBaseAccess <Your-Zookeeper-IP> get 20 100

The result is shown in the following figure.

Read HBase table

Benchmark results and key learning

For the three scenarios, we use 100 HBase record row keys as input, ensure these row keys distributed evenly in HBase table regions, we call the API consecutively with 20 times, 50 times, and 100 times, and we got the time cost result as the following figure. We found the read latency is the shortest when the data is on S3 and using BucketCache.

Read performance

Above, we introduced four migration scenarios. In migration processes in production, we’ve gained invaluable knowledge and experience. We’re sharing the results here for you to use as best practices and a recommended run book.

Configuration parameters

In the configurations provided earlier, some are necessary for BucketCache settings while others mitigate known errors to reduce the snapshot duration. For example, the parameter hbase.snapshot.master.timeout.millis is related to the HBASE-14680 issue. It’s advisable to retain these configurations as much as possible throughout the migration process.

Version choice

When migrating to Amazon EMR and choosing a suitable HBase version, it is recommended to select a more recent minor version and patch version, while keeping the major version unchanged. That is to say:

  • If the source HBase is version 1.x, we recommend using EMR 5.36.1, whose HBase version is 1.4.13, because the HBase 1.x API is compatible and won’t require you to make code changes.
  • If the source HBase is version 2.x, we recommend using EMR 6.15.0, which has an HBase of 2.4.17.

The HBase API under the same major version can be universal. See HBase Version to learn more.

Allocating enough space

HDFS needs to leave enough space when exporting snapshots, it depends on the data volume. Data will be moved to the archive, causing double storage is needed for the table.

Replication

At present, there is compatibility problem if replication and WAL compression are used together. If you are using replication, set the hbase.regionserver.wal.enablecompression property to false. See HBASE-26849 for more information.

By default, replication in HBase is asynchronous, as the write-ahead log (WAL) is sent to another cluster in the background. This implies that when using replication for data recovery, some data loss may occur. Additionally, there is a potential for data overwrite conflicts when concurrently writing the same record within a short time frame. However, HBase v2.x introduces synchronous replication as a solution to this issue. For more details, refer to the Serial Replication documentation.

Disk type for BucketCache

Because BucketCache uses a portion of Amazon EBS IO and throughput to synchronize data, it’s recommended to choose Amazon EBS gp3 volumes for their higher IOPS and throughput.

Response latency when accessing to HBase

Users sometimes face the issue of high response latency from their Hbase on EMR clusters using API calls or the HBase shell tool.

In our testing, we found that the communication between HMaster and RegionServer takes an unusually long time to resolve through DNS. You can reduce latency by adding the host name and IP mapping to the /etc/hosts file in the HBase client host.

Conclusion

In this post, we used the results of real-world migration cases to introduce the process of migrating HBase to Amazon EMR HBase using HBase snapshot and replication and the deployment mode of HBase on Amazon S3. We included how to resolve challenges, such as how to configure the cluster to make the migration process smoother when migrating a single large table, or how to use BucketCache to improve reading performance. We also described techniques for testing performance.

We encourage you to migrate HBase to Amazon EMR HBase. For more information about HBase migration, see Amazon EMR HBase best practices.


About the Authors

Dalei XuDalei Xu is a Analytics Specialist Solution Architect at Amazon Web Services, responsible for consulting, designing, and implementing AWS data analytics solutions. With over 20 years of experience in data-related work, proficient in data development, migration to AWS, architecture design, and performance optimization. Hoping to promote AWS data analytics services to more customers, achieving a win-win situation and mutual growth with customers.

Zhiyong Su is a Migration Specialist Solution Architect at Amazon Web Services, primarily responsible for cloud migration or cross-cloud migration for enterprise-level clients. Has held positions such as R&D Engineer, Solutions Architect, and has years of practical experience in IT professional services and enterprise application architecture.

Shijian TangShijian Tang is a Analytics Specialist Solution Architect at Amazon Web Services.

Enhance Amazon EMR scaling capabilities with Application Master Placement

Post Syndicated from Lorenzo Ripani original https://aws.amazon.com/blogs/big-data/enhance-amazon-emr-scaling-capabilities-with-application-master-placement/

In today’s data-driven world, processing large datasets efficiently is crucial for businesses to gain insights and maintain a competitive edge. Amazon EMR is a managed big data service designed to handle these large-scale data processing needs across the cloud. It allows running applications built using open source frameworks on Amazon Elastic Compute Cloud (Amazon EC2), Amazon Elastic Kubernetes Service (Amazon EKS), or AWS Outposts, or completely serverless. One of the key features of Amazon EMR on EC2 is managed scaling, which dynamically adjusts computing capacity in response to application demands, providing optimal performance and cost-efficiency.

Although managed scaling aims to optimize EMR clusters for best price-performance and elasticity, some use cases require more granular resource allocation. For example, when multiple applications are submitted to the same clusters, resource contention may occur, potentially impacting both performance and cost-efficiency. Additionally, allocating the Application Master (AM) container to non-reliable nodes like Spot can potentially result in loss of the container and immediate shutdown of the entire YARN application, resulting in wasted resources and additional costs for rescheduling the entire YARN application. These uses cases require more granular resource allocation and sophisticated scheduling policies to optimize resource utilization and maintain high performance.

Starting with the Amazon EMR 7.2 release, Amazon EMR on EC2 introduced a new feature called Application Master (AM) label awareness, which allows users to enable YARN node labels to allocate the AM containers within On-Demand nodes only. Because the AM container is responsible for orchestrating the overall job execution, it’s crucial to verify that it gets allocated to a reliable instance and not be subjected to shutdown due to Spot Instance interruption. Additionally, limiting AM containers to On-Demand helps maintain consistent application launch time, because the fulfillment of the On-Demand Instance isn’t prone to unavailable Spot capacity or bid price.

In this post, we explore the key features and use cases where this new functionality can provide significant benefits, enabling cluster administrators to achieve optimal resource utilization, improved application reliability, and cost-efficiency in your EMR on EC2 clusters.

Solution overview

The Application Master label awareness feature in Amazon EMR works in conjunction with YARN node labels, a functionality offered by Hadoop that empowers you to define labels to nodes within a Hadoop cluster. You can use these labels to determine which nodes of the cluster should host specific YARN containers (such as mappers vs. reducers in a MapReduce, or drivers vs. executors in Apache Spark).

This feature is enabled by default when a cluster is launched with Amazon EMR 7.2.0 and later using Amazon EMR managed scaling, and it has been configured to use YARN node labels. The following code is a basic configuration setup that enables this feature:

[
   {
     "Classification": "yarn-site",
     "Properties": {
      "yarn.node-labels.enabled": "true",
       "yarn.node-labels.am.default-node-label-expression": "ON_DEMAND"
     }
   }
]

Within this configuration snippet, we activate the Hadoop node label feature and define a value for the yarn.node-labels.am.default-node-label-expression property. This property defines the YARN node label that will be used to schedule the AM container of each YARN application submitted to the cluster. This specific container plays a key role in maintaining the lifecycle of the workflow, so verifying its placement on reliable nodes in production workloads is crucial, because the unexpected shutdown of this container can result in the shutdown and failure of the entire application.

Currently, the Application Master label awareness feature only supports two predefined node labels that can be specified to allocate the AM container of a YARN job: ON_DEMAND and CORE. When one of these labels is defined using Amazon EMR configurations (see the preceding example code), Amazon EMR automatically creates the corresponding node labels in YARN and labels the instances in the cluster accordingly.

To demonstrate how this feature works, we launch a sample cluster and run some Spark jobs to see how Amazon EMR managed scaling integrates with YARN node labels.

Launch an EMR cluster with Application Manager placement awareness

To perform some tests, you can launch the following AWS CloudFormation stack, which provisions an EMR cluster with managed scaling and the Application Manager placement awareness feature enabled. If this is your first time launching an EMR cluster, make sure to create the Amazon EMR default roles using the following AWS Command Line Interface (AWS CLI) command:

aws emr create-default-roles

To create the cluster, choose Launch Stack:

Launch Cloudformation Stack

Provide the following required parameters:

  • VPC – An existing virtual private cloud (VPC) in your account where the cluster will be provisioned
  • Subnet – The subnet in your VPC where you want to launch the cluster
  • SSH Key Name – An EC2 key pair that you use to connect to the EMR primary node

After the EMR cluster has been provisioned, establish a tunnel to the Hadoop Resource Manager web UI to review the cluster configurations. To access the Resource Manager web UI, complete the following steps:

  1. Set up an SSH tunnel to the primary node using dynamic port forwarding.
  2. Point your browser to the URL http://<primary-node-public-dns>:8088/, using the public DNS name of your cluster’s primary node.

This will open the Hadoop Resource Manager web UI, where you can see how the cluster has been configured.

YARN node labels

In the CloudFormation stack, you launched a cluster specifying to allocate the AM containers on nodes labeled as ON_DEMAND. If you explore the Resource Manager web UI, you can see that Amazon EMR created two labels in the cluster: ON_DEMAND and SPOT. To review the YARN node labels present in your cluster, you can inspect the Node Labels page, as shown in the following screenshot.

On this page, you can see how the YARN labels were created in Amazon EMR:

  • During initial cluster creation, default node labels such as ON_DEMAND and SPOT are automatically generated as non-exclusive partitions
  • The DEFAULT_PARTITION label stays vacant because every node gets labeled based on its market type—either being an On-Demand or Spot Instance

In our example, because we launched a single core node as On-Demand, you can observe a single node assigned to the ON_DEMAND partition, and the SPOT partition remains empty. Because the labels are created as non-exclusive, nodes with these labels can run both containers launched with a specific YARN label and also containers that don’t specify a YARN label. For additional details on YARN node labels, see YARN Node Labels in the Hadoop documentation.

Now that we have discussed how the cluster was configured, we can perform some tests to validate and review the behavior of this feature when using it in combination with managed scaling.

Concurrent application submission with Spot Instances

To test the managed scaling capabilities, we submit a simple SparkPi job configured to utilize all available memory on the single core node initially launched in our cluster:

spark-example \
  --deploy-mode cluster \
  --driver-memory 10g \
  --executor-memory 10g \
  --conf spark.dynamicAllocation.maxExecutors=1 \
  --conf spark.yarn.executor.nodeLabelExpression=SPOT \
  SparkPi 800000

In the preceding snippet, we tuned specific Spark configurations to utilize all the resources of the cluster nodes launched (you could also achieve this using the maximizeResourceAllocation configuration while launching an EMR cluster). Because the cluster has been launched using m5.xlarge instances, we can launch individual containers up to 12 GB in terms of memory requirements. With these assumptions, the snippet configures the following:

  • The Spark driver and executors were configured with 10 GB of memory to utilize most of the available memory on the node, in order to have a single container running on each node of our cluster and simplify this example.
  • The node-labels.am.default-node-label-expression parameter was set to ON_DEMAND, making sure the Spark driver is automatically allocated to the ON_DEMAND partition of our cluster. Because we specified this configuration while launching the cluster, the AM containers are automatically requested to be scheduled on ON_DEMAND labeled instances, so we don’t need to specify it at the job level.
  • The yarn.executor.nodeLabelExpression=SPOT configuration verifies that the executors operated exclusively on TASK nodes using Spot Instances. Removing this configuration allows the Spark executors to be scheduled both on SPOT and ON_DEMAND labeled nodes.
  • The dynamicAllocation.maxExecutors setting was set to 1 to delay the processing time of the application and observe the scaling behavior when multiple YARN applications were submitted concurrently in the same cluster.

As the application transitioned to a RUNNING state, we can verify from the YARN Resource Manager UI that its driver placement was automatically assigned to the ON_DEMAND partition of our cluster (see the following screenshot).

Additionally, upon inspecting the YARN scheduler page, we can see that our SPOT partition doesn’t have a resource associated with it because the cluster was launched with just one On-Demand Instance.

Because the cluster didn’t have Spot Instances initially, you can observe from the Amazon EMR console that managed scaling generates a new Spot task group to accommodate the Spark executor requested to run on Spot nodes only (see the following screenshot) . Before this integration, managed scaling didn’t take into account the YARN labels requested by an application, potentially leading to unpredictable scaling behaviors. With this release, managed scaling now considers the YARN labels specified by applications, enabling more predictable and accurate scaling decisions.

While waiting for the launch of the new Spot node, we submitted another SparkPi job with identical specifications. However, because the memory required to allocate the new Spark Driver was 10 GB and such resources were currently unavailable in the ON_DEMAND partition, the application remained in a pending state until resources became available to schedule its container.

Upon detecting the lack of resources to allocate the new Spark driver, Amazon EMR managed scaling commenced scaling the core instance group (On-Demand Instances in our cluster) by launching a new core node. After the new core node was launched, YARN promptly allocated the pending container on the new node, enabling the application to start its processing. Subsequently, the application requested additional Spot nodes to allocate its own executors (see the following screenshot).

This example demonstrates how managed scaling and YARN labels work together to improve the resiliency of YARN applications, while using cost-effective job executions over Spot Instances.

When to use Application Manager placement awareness and managed scaling

You can use this placement awareness feature to improve cost-efficiency by using Spot Instances while protecting the Application Manager from being incorrectly shut down due to Spot interruptions. It’s particularly useful when you want to take advantage of the cost savings offered by Spot Instances while preserving the stability and reliability of your jobs running on the cluster. When working with managed scaling and the placement awareness feature, consider the following best practices:

  • Maximum cost-efficiency for non-critical jobs – If you have jobs that don’t have strict service level agreement (SLA) requirements, you can force all Spark executors to run on Spot Instances for maximum cost savings. This can be achieved by setting the following Spark configuration:
    spark.yarn.executor.nodeLabelExpression=SPOT

  • Resilient execution for production jobs – For production jobs where you require a more resilient execution, you might consider not setting the yarn.executor.nodeLabelExpression parameter. When no label is specified, executors are dynamically allocated between both On-Demand and Spot nodes, providing a more reliable execution.
  • Limit dynamic allocation for concurrent applications – When working with managed scaling and clusters with multiple applications running concurrently (for example, an interactive cluster with concurrent user utilization), you should consider setting a maximum limit for Spark dynamic allocation using the dynamicAllocation.maxExecutors setting. This can help manage resources over-provisioning and facilitate predictable scaling behavior across applications running on the same cluster. For more details, see Dynamic Allocation in the Spark documentation.
  • Managed scaling configurations – Make sure your managed scaling configurations are set up correctly to facilitate efficient scaling of Spot Instances based on your workload requirements. For example, set an appropriate value for Maximum On-Demand instances in managed scaling based on the number of concurrent applications you want to run on the cluster. Additionally, if you’re planning to use your On-Demand Instances for running solely AM containers, we recommend setting scheduler.capacity.maximum-am-resource-percent to 1 using the Amazon EMR capacity-scheduler classification.
  • Improve startup time of the nodes – If your cluster is subject to frequent scaling events (for example, you have a long-running cluster that can run multiple concurrent EMR steps), you might want to optimize the startup time of your cluster nodes. When trying to get an efficient node startup, consider only installing the minimum required set of application frameworks in the cluster and, whenever possible, avoid installing non-YARN frameworks such as HBase or Trino, which might delay the startup of processing nodes dynamically attached by Amazon EMR managed scaling. Finally, whenever possible, don’t use complex and time-consuming EMR bootstrap actions to avoid increasing the startup time of nodes launched with managed scaling.

By following these best practices, you can take advantage of the cost savings of Spot Instances while maintaining the stability and reliability of your applications, particularly in scenarios where multiple applications are running concurrently on the same cluster.

Conclusion

In this post, we explored the benefits of the new integration between Amazon EMR managed scaling and YARN node labels, reviewed its implementation and usage, and defined a few best practices that can help you get started. Whether you’re running batch processing jobs, stream processing applications, or other YARN workloads on Amazon EMR, this feature can help you achieve substantial cost savings without compromising on performance or reliability.

As you embark on your journey to use Spot Instances in your EMR clusters, remember to follow the best practices outlined in this post, such as setting appropriate configurations for dynamic allocation, node label expressions, and managed scaling policies. By doing so, you can make sure that your applications run efficiently, reliably, and at the lowest possible cost.


About the authors

Lorenzo Ripani is a Big Data Solution Architect at AWS. He is passionate about distributed systems, open source technologies and security. He spends most of his time working with customers around the world to design, evaluate and optimize scalable and secure data pipelines with Amazon EMR.

Miranda Diaz is a Software Development Engineer for EMR at AWS. Miranda works to design and develop technologies that make it easy for customers across the world to automatically scale their computing resources to their needs, helping them achieve the best performance at the optimal cost.

Sajjan Bhattarai is a Senior Cloud Support Engineer at AWS, and specializes in BigData and Machine Learning workloads. He enjoys helping customers around the world to troubleshoot and optimize their data platforms.

Bezuayehu Wate is an Associate Big Data Specialist Solutions Architect at AWS. She works with customers to provide strategic and architectural guidance on designing, building, and modernizing their cloud-based analytics solutions using AWS.

Amazon EMR on EC2 cost optimization: How a global financial services provider reduced costs by 30%

Post Syndicated from Omar Gonzalez original https://aws.amazon.com/blogs/big-data/amazon-emr-on-ec2-cost-optimization-how-a-global-financial-services-provider-reduced-costs-by-30/

In this post, we highlight key lessons learned while helping a global financial services provider migrate their Apache Hadoop clusters to AWS and best practices that helped reduce their Amazon EMR, Amazon Elastic Compute Cloud (Amazon EC2), and Amazon Simple Storage Service (Amazon S3) costs by over 30% per month.

We outline cost-optimization strategies and operational best practices achieved through a strong collaboration with their DevOps teams. We also discuss a data-driven approach using a hackathon focused on cost optimization along with Apache Spark and Apache HBase configuration optimization.

Background

In early 2022, a business unit of a global financial services provider began their journey to migrate their customer solutions to AWS. This included web applications, Apache HBase data stores, Apache Solr search clusters, and Apache Hadoop clusters. The migration included over 150 server nodes and 1 PB of data. The on-premises clusters supported real-time data ingestion and batch processing.

Because of aggressive migration timelines driven by the closure of data centers, they implemented a lift-and-shift rehosting strategy of their Apache Hadoop clusters to Amazon EMR on EC2, as highlighted in the Amazon EMR migration guide.

Amazon EMR on EC2 provided the flexibility for the business unit to run their applications with minimal changes on managed Hadoop clusters with the required Spark, Hive, and HBase software and versions installed. Because the clusters are managed, they were able to decompose their large on-premises cluster and deploy purpose-built transient and persistent clusters for each use case on AWS without increasing operational overhead.

Challenge

Although the lift-and-shift strategy allowed the business unit to migrate with lower risk and allowed their engineering teams to focus on product development, this came with increased ongoing AWS costs.

The business unit deployed transient and persistent clusters for different use cases. Several application components relied on Spark Streaming for real-time analytics, which was deployed on persistent clusters. They also deployed the HBase environment on persistent clusters.

After the initial deployment, they discovered several configuration issues that led to suboptimal performance and increased cost. Despite using Amazon EMR managed scaling for persistent clusters, the configuration wasn’t efficient due to setting a minimum of 40 core nodes and task nodes, resulting in wasted resources. Core nodes were also misconfigured to auto scale. This led to scale-in events shutting down core nodes with shuffle data. The business unit also implemented Amazon EMR auto-termination policies. Because of shuffle data loss on the EMR on EC2 clusters running Spark applications, certain jobs ran five times longer than planned. Here, auto-termination policies didn’t mark a cluster as idle because a job was still running.

Lastly, there were separate environments for development (dev), user acceptance testing (UAT), production (prod), which were also over-provisioned with the minimum capacity units for the managed scaling policies configured too high, leading to higher costs as shown in the following figure.

Short-term cost-optimization strategy

The business unit completed the migration of applications, databases, and Hadoop clusters in 4 months. Their immediate goal was to get out of their data centers as quickly as possible, followed by cost optimization and modernization. Although they expected greater upfront costs because of the lift-and-shift approach, their costs were 40% higher than forecasted. This sped up their need to optimize.

They engaged with their shared services team and the AWS team to develop a cost-optimization strategy. The business unit began by focusing on cost-optimization best practices to implement immediately that didn’t require product development team engagement or impact their productivity. They performed a cost analysis to determine the largest contributors of cost were EMR on EC2 clusters running Spark, EMR on EC2 clusters running HBase, Amazon S3 storage, and EC2 instances running Solr.

The business unit started by enforcing auto-termination of EMR clusters in their dev environments by using automation. They considered using Amazon EMR isIdle Amazon CloudWatch metrics to build an event-driven solution with AWS Lambda, as described in Optimize Amazon EMR costs with idle checks and automatic resource termination using advanced Amazon CloudWatch metrics and AWS Lambda. They implemented a stricter policy to shut down clusters in their lower environments after 3 hours, regardless of usage. They also updated managed scaling policies in DEV and UAT and set the minimum cluster size to three instances to allow clusters to scale up as needed. This resulted in a 60% savings in monthly dev and UAT costs over 5 months, as shown in the following figure.

For the initial production deployment, they had a subset of Spark jobs running on a persistent cluster with an older Amazon EMR 5.(x) release. To optimize costs, they split smaller jobs and larger jobs to run on separate persistent clusters and configured the minimum number of core nodes required to support jobs in each cluster. Setting the core nodes to a constant size while using managed scaling for only task nodes is a recommended best practice and eliminated the issue of shuffle data loss. This also improved the time to scale in and out, because task nodes don’t store data in Hadoop Distributed File System (HDFS).

Solr clusters ran on EC2 instances. To optimize this environment, they ran performance tests to determine the best EC2 instances for their workload.

With over one petabyte of data, Amazon S3 contributed to over 15% of monthly costs. The business unit enabled the Amazon S3 Intelligent-Tiering storage class to optimize storage expenses for historical data and reduce their monthly Amazon S3 costs by over 40%, as shown in the following figure. They also migrated Amazon Elastic Block Store (Amazon EBS) volumes from gp2 to gp3 volume types.

Longer-term cost-optimization strategy

After the business unit realized initial cost savings, they engaged with the AWS team to organize a financial hackathon (FinHack) event. The goal of the hackathon was to reduce costs further by using a data-driven process to test cost-optimization strategies for Spark jobs. To prepare for the hackathon, they identified a set of jobs to test using different Amazon EMR deployment options (Amazon EC2, Amazon EMR Serverless) and configurations (Spot, AWS Graviton, Amazon EMR managed scaling, EC2 instance fleets) to arrive at the most cost-optimized solution for each job. A sample test plan for a job is shown in the following table. The AWS team also assisted with analyzing Spark configurations and job execution during the event.

Job Test Description Configuration
Job 1 1 Run an EMR on EC2 job with default Spark configurations Non Graviton, On-Demand Instances
2 Run an EMR on Serverless job with default Spark configurations Default configuration
3 Run an EMR on EC2 job with default Spark configuration and Graviton instances Graviton, On-Demand Instances
4 Run an EMR on EC2 job with default Spark configuration and Graviton instances. Hybrid Spot Instance allocation. Graviton, On-Demand and Spot Instances

The business unit also performed extensive testing using Spot Instances before and during the FinHack. They initially used the Spot Instance advisor and Spot Blueprints to create optimal instance fleet configurations. They automated the process to select the most optimal Availability Zone to run jobs by querying for the Spot placement scores using the get_spot_placement_scores API before launching new jobs.

During the FinHack, they also developed an EMR job tracking script and report to granularly track cost per job and measure ongoing improvements. They used the AWS SDK for Python (Boto3) to list the status of all transient clusters in their account and report on cluster-level configurations and instance hours per job.

As they executed the test plan, they found several additional areas of enhancement:

  • One of the test jobs makes API calls to Solr clusters, which introduced a bottleneck in the design. To prevent Spark jobs from overwhelming the clusters, they fine-tuned executor.cores and spark.dynamicAllocation.maxExecutors properties.
  • Task nodes were over-provisioned with large EBS volumes. They reduced the size to 100 GB for additional cost savings.
  • They updated their instance fleet configuration by setting unit/weights proportional based on instance types selected.
  • During the initial migration, they set the spark.sql.shuffle.paritions configuration too high. The configuration was fine-tuned for their on-premises cluster but not updated to align with their EMR clusters. They optimized the configuration by setting the value to one or two times the number of vCores in the cluster .

Following the FinHack, they enforced a cost allocation tagging strategy for persistent clusters that are deployed using Terraform and transient clusters deployed using Amazon Managed Workflows for Apache Airflow (Amazon MWAA). They also deployed an EMR Observability dashboard using Amazon Managed Service for Prometheus and Amazon Managed Grafana.

Results

The business unit reduced monthly costs by 30% over 3 months. This allowed them to continue migration efforts of remaining on-premises workloads. Most of their 2,000 jobs per month now run on EMR transient clusters. They have also increased AWS Graviton usage to 40% of total usage hours per month and Spot usage to 10% in non-production environments.

Conclusion

Through a data-driven approach involving cost analysis, adherence to AWS best practices, configuration optimization, and extensive testing during a financial hackathon, the global financial services provider successfully reduced their AWS costs by 30% over 3 months. Key strategies included enforcing auto-termination policies, optimizing managed scaling configurations, using Spot Instances, adopting AWS Graviton instances, fine-tuning Spark and HBase configurations, implementing cost allocation tagging, and developing cost tracking dashboards. Their partnership with AWS teams and a focus on implementing short-term and longer-term best practices allowed them to continue their cloud migration efforts while optimizing costs for their big data workloads on Amazon EMR.

For additional cost-optimization best practices, we recommend visiting AWS Open Data Analytics.


About the Authors

Omar Gonzalez is a Senior Solutions Architect at Amazon Web Services in Southern California with more than 20 years of experience in IT. He is passionate about helping customers drive business value through the use of technology. Outside of work, he enjoys hiking and spending quality time with his family.

Navnit Shukla, an AWS Specialist Solution Architect specializing in Analytics, is passionate about helping clients uncover valuable insights from their data. Leveraging his expertise, he develops inventive solutions that empower businesses to make informed, data-driven decisions. Notably, Navnit Shukla is the accomplished author of the book Data Wrangling on AWS, showcasing his expertise in the field. He also runs the YouTube channel Cloud and Coffee with Navnit, where he shares insights on cloud technologies and analytics. Connect with him on LinkedIn.

Amazon EMR Serverless observability, Part 1: Monitor Amazon EMR Serverless workers in near real time using Amazon CloudWatch

Post Syndicated from Kashif Khan original https://aws.amazon.com/blogs/big-data/amazon-emr-serverless-observability-part-1-monitor-amazon-emr-serverless-workers-in-near-real-time-using-amazon-cloudwatch/

Amazon EMR Serverless allows you to run open source big data frameworks such as Apache Spark and Apache Hive without managing clusters and servers. With EMR Serverless, you can run analytics workloads at any scale with automatic scaling that resizes resources in seconds to meet changing data volumes and processing requirements.

We have launched job worker metrics in Amazon CloudWatch for EMR Serverless. This feature allows you to monitor vCPUs, memory, ephemeral storage, and disk I/O allocation and usage metrics at an aggregate worker level for your Spark and Hive jobs.

This post is part of a series about EMR Serverless observability. In this post, we discuss how to use these CloudWatch metrics to monitor EMR Serverless workers in near real time.

CloudWatch metrics for EMR Serverless

At the per-Spark job level, EMR Serverless emits the following new metrics to CloudWatch for both driver and executors. These metrics provide granular insights into job performance, bottlenecks, and resource utilization.

WorkerCpuAllocated The total numbers of vCPU cores allocated for workers in a job run
WorkerCpuUsed The total numbers of vCPU cores utilized by workers in a job run
WorkerMemoryAllocated The total memory in GB allocated for workers in a job run
WorkerMemoryUsed The total memory in GB utilized by workers in a job run
WorkerEphemeralStorageAllocated The number of bytes of ephemeral storage allocated for workers in a job run
WorkerEphemeralStorageUsed The number of bytes of ephemeral storage used by workers in a job run
WorkerStorageReadBytes The number of bytes read from storage by workers in a job run
WorkerStorageWriteBytes The number of bytes written to storage from workers in a job run

The following are the benefits of monitoring your EMR Serverless jobs with CloudWatch:

  • Optimize resource utilization – You can gain insights into resource utilization patterns and optimize your EMR Serverless configurations for better efficiency and cost savings. For example, underutilization of vCPUs or memory can reveal resource wastage, allowing you to optimize worker sizes to achieve potential cost savings.
  • Diagnose common errors – You can identify root causes and mitigation for common errors without log diving. For example, you can monitor the usage of ephemeral storage and mitigate disk bottlenecks by preemptively allocating more storage per worker.
  • Gain near real-time insights – CloudWatch offers near real-time monitoring capabilities, allowing you to track the performance of your EMR Serverless jobs as and when they are running, for quick detection of any anomalies or performance issues.
  • Configure alerts and notifications – CloudWatch enables you to set up alarms using Amazon Simple Notification Service (Amazon SNS) based on predefined thresholds, allowing you to receive notifications through email or text message when specific metrics reach critical levels.
  • Conduct historical analysis – CloudWatch stores historical data, allowing you to analyze trends over time, identify patterns, and make informed decisions for capacity planning and workload optimization.

Solution overview

To further enhance this observability experience, we have created a solution that gathers all these metrics on a single CloudWatch dashboard for an EMR Serverless application. You need to launch one AWS CloudFormation template per EMR Serverless application. You can monitor all the jobs submitted to a single EMR Serverless application using the same CloudWatch dashboard. To learn more about this dashboard and deploy this solution into your own account, refer to the EMR Serverless CloudWatch Dashboard GitHub repository.

In the following sections, we walk you through how you can use this dashboard to perform the following actions:

  • Optimize your resource utilization to save costs without impacting job performance
  • Diagnose failures due to common errors without the need for log diving and resolve those errors optimally

Prerequisites

To run the sample jobs provided in this post, you need to create an EMR Serverless application with default settings using the AWS Management Console or AWS Command Line Interface (AWS CLI), and then launch the CloudFormation template from the GitHub repo with the EMR Serverless application ID provided as the input to the template.

You need to submit all the jobs in this post to the same EMR Serverless application. If you want to monitor a different application, you can deploy this template for your own EMR Serverless application ID.

Optimize resource utilization

When running Spark jobs, you often start with the default configurations. It can be challenging to optimize your workload without any visibility into actual resource utilization. Some of the most common configurations that we’ve seen customers adjust are spark.driver.cores, spark.driver.memory, spark.executor.cores, and spark.executors.memory.

To illustrate how the newly added CloudWatch dashboard worker-level metrics can help you fine-tune your job configurations for better price-performance and enhanced resource utilization, let’s run the following Spark job, which uses the NOAA Integrated Surface Database (ISD) dataset to run some transformations and aggregations.

Use the following command to run this job on EMR Serverless. Provide your Amazon Simple Storage Service (Amazon S3) bucket and EMR Serverless application ID for which you launched the CloudFormation template. Make sure to use the same application ID to submit all the sample jobs in this post. Additionally, provide an AWS Identity and Access Management (IAM) runtime role.

aws emr-serverless start-job-run \
--name emrs-cw-dashboard-test-1 \
 --application-id <APPLICATION_ID> \
 --execution-role-arn <JOB_ROLE_ARN> \
 --job-driver '{
 "sparkSubmit": {
 "entryPoint": "s3://<BUCKETNAME>/scripts/windycity.py",
 "entryPointArguments": ["s3://noaa-global-hourly-pds/2024/", "s3://<BUCKET_NAME>/emrs-cw-dashboard-test-1/"]
 } }'

Now let’s check the executor vCPUs and memory from the CloudWatch dashboard.

This job was submitted with default EMR Serverless Spark configurations. From the Executor CPU Allocated metric in the preceding screenshot, the job was allocated 396 vCPUs in total (99 executors * 4 vCPUs per executor). However, the job only used a maximum of 110 vCPUs based on Executor CPU Used. This indicates oversubscription of vCPU resources. Similarly, the job was allocated 1,584 GB memory in total based on Executor Memory Allocated. However, from the Executor Memory Used metric, we see that the job only used 176 GB of memory during the job, indicating memory oversubscription.

Now let’s rerun this job with the following adjusted configurations.

Original Job (Default Configuration) Rerun Job (Adjusted Configuration)
spark.executor.memory 14 GB 3 GB
spark.executor.cores 4 2
spark.dynamicAllocation.maxExecutors 99 30
Total Resource Utilization

6.521 vCPU-hours

26.084 memoryGB-hours

32.606 storageGB-hours

1.739 vCPU-hours

3.688 memoryGB-hours

17.394 storageGB-hours

Billable Resource Utilization

7.046 vCPU-hours

28.182 memoryGB-hours

0 storageGB-hours

1.739 vCPU-hours

3.688 memoryGB-hours

0 storageGB-hours

We use the following code:

aws emr-serverless start-job-run \
--name emrs-cw-dashboard-test-2 \
 --application-id <APPLICATION_ID> \
 --execution-role-arn <JOB_ROLE_ARN> \
 --job-driver '{
 "sparkSubmit": {
 "entryPoint": "s3://<BUCKETNAME>/scripts/windycity.py",
 "entryPointArguments": ["s3://noaa-global-hourly-pds/2024/", "s3://<BUCKET_NAME>/emrs-cw-dashboard-test-2/"],
 "sparkSubmitParameters": "--conf spark.driver.cores=2 --conf spark.driver.memory=3g --conf spark.executor.memory=3g --conf spark.executor.cores=2 --conf spark.dynamicAllocation.maxExecutors=30"
 } }'

Let’s check the executor metrics from the CloudWatch dashboard again for this job run.

In the second job, we see lower allocation of both vCPUs (396 vs. 60) and memory (1,584 GB vs. 120 GB) as expected, resulting in better utilization of resources. The original job ran for 4 minutes, 41 seconds. The second job took 4 minutes, 54 seconds. This reconfiguration has resulted in 79% lower cost savings without affecting the job performance.

You can use these metrics to further optimize your job by increasing or decreasing the number of workers or the allocated resources.

Diagnose and resolve job failures

Using the CloudWatch dashboard, you can diagnose job failures due to issues related to CPU, memory, and storage such as out of memory or no space left on the device. This enables you to identify and resolve common errors quickly without having to check the logs or navigate through Spark History Server. Additionally, because you can check the resource utilization from the dashboard, you can fine-tune the configurations by increasing the required resources only as much as needed instead of oversubscribing to the resources, which further saves costs.

Driver errors

To illustrate this use case, let’s run the following Spark job, which creates a large Spark data frame with a few million rows. Typically, this operation is done by the Spark driver. While submitting the job, we also configure spark.rpc.message.maxSize, because it’s required for task serialization of data frames with a large number of columns.

aws emr-serverless start-job-run \
--name emrs-cw-dashboard-test-3 \
--application-id <APPLICATION_ID> \
--execution-role-arn <JOB_ROLE_ARN> \
--job-driver '{
"sparkSubmit": {
"entryPoint": "s3://<BUCKETNAME>/scripts/create-large-disk.py"
"sparkSubmitParameters": "--conf spark.rpc.message.maxSize=2000"
} }'

After a few minutes, the job failed with the error message “Encountered errors when releasing containers,” as seen in the Job details section.

When encountering non-descriptive error messages, it becomes crucial to investigate further by examining the driver and executor logs to troubleshoot further. But before further log diving, let’s first check the CloudWatch dashboard, specifically the driver metrics, because releasing containers is generally performed by the driver.

We can see that the Driver CPU Used and Driver Storage Used are well within their respective allocated values. However, upon checking Driver Memory Allocated and Driver Memory Used, we can see that the driver was using all of the 16 GB memory allocated to it. By default, EMR Serverless drivers are assigned 16 GB memory.

Let’s rerun the job with more driver memory allocated. Let’s set driver memory to 27 GB as the starting point, because spark.driver.memory + spark.driver.memoryOverhead should be less than 30 GB for the default worker type. park.rpc.messsage.maxSize will be unchanged.

aws emr-serverless start-job-run \
—name emrs-cw-dashboard-test-4 \
—application-id <APPLICATION_ID> \
—execution-role-arn <JOB_ROLE_ARN> \
—job-driver '{
"sparkSubmit": {
"entryPoint": "s3://<BUCKETNAME>/scripts/create-large-disk.py"
"sparkSubmitParameters": "--conf spark.driver.memory=27G --conf spark.rpc.message.maxSize=2000"
} }'

The job succeeded this time around. Let’s check the CloudWatch dashboard to observe driver memory utilization.

As we can see, the allocated memory is now 30 GB, but the actual driver memory utilization didn’t exceed 21 GB during the job run. Therefore, we can further optimize costs here by reducing the value of spark.driver.memory. We reran the same job with spark.driver.memory set to 22 GB, and the job still succeeded with better driver memory utilization.

Executor errors

Using CloudWatch for observability is ideal for diagnosing driver-related issues because there is only one driver per job and driver resources used is the actual resource usage of the single driver. On the other hand, executor metrics are aggregated across all the workers. However, you can use this dashboard to provide only an adequate amount of resources to make your job succeed, thereby avoiding oversubscription of resources.

To illustrate, let’s run the following Spark job, which simulates uniform disk over-utilization across all workers by processing very large NOAA datasets from several years. This job also transiently caches a very large data frame on disk.

aws emr-serverless start-job-run \
--name emrs-cw-dashboard-test-5 \
--application-id <APPLICATION_ID> \
--execution-role-arn <JOB_ROLE_ARN> \
--job-driver '{
"sparkSubmit": {
"entryPoint": "s3://<BUCKETNAME>/scripts/noaa-disk.py"
} }'

After a few minutes, we can see that the job failed with “No space left on device” error in the Job details section, which indicates that some of the workers have run out of disk space.

Checking the Running Executors metric from the dashboard, we can identify that there were 99 executor workers running. Each worker comes with 20 GB storage by default.

Because this is a Spark task failure, let’s check the Executor Storage Allocated and Executor Storage Used metrics from the dashboard (because the driver won’t run any tasks).

As we can see, the 99 executors have used up a total of 1,940 GB from the total allocated executor storage of 2,126 GB. This includes both the data shuffled by the executors and the storage used for caching the data frame. We don’t see the full 2,126 GB being utilized from this graph because there might be a few executors out of the 99 executors that weren’t holding much data when the job failed (before these executors could start processing tasks and store the data frame chunks).

Let’s rerun the same job but with increased executor disk size using the parameter spark.emr-serverless.executor.disk. Let’s try with 40 GB disk per executor as a starting point.

aws emr-serverless start-job-run \
--name emrs-cw-dashboard-test-6 \
--application-id <APPLICATION_ID> \
--execution-role-arn <JOB_ROLE_ARN> \
--job-driver '{
"sparkSubmit": {
"entryPoint": "s3://<BUCKETNAME>/scripts/noaa-disk.py"
"sparkSubmitParameters": "--conf spark.emr-serverless.executor.disk=40G"
}
}'

This time, the job ran successfully. Let’s check the Executor Storage Allocated and Executor Storage Used metrics.

Executor Storage Allocated is now 4,251 GB because we’ve doubled the value of spark.emr-serverless.executor.disk. Although there is now twice as much aggregated executors’ storage, the job still used only a maximum of 1,940 GB out of 4,251 GB. This indicates that our executors were likely running out of disk space only by a few GBs. Therefore, we can try to set spark.emr-serverless.executor.disk to an even lower value like 25 GB or 30 GB instead of 40 GB to save storage costs as we did in the previous scenario. In addition, you can monitor Executor Storage Read Bytes and Executor Storage Write Bytes to see if your job is I/O intensive. In this case, you can use the Shuffle-optimized disks feature of EMR Serverless to further enhance your job’s I/O performance.

The dashboard is also useful to capture information about transient storage used while caching or persisting the data frames, including spill-to-disk scenarios. The Storage tab of Spark History Server records any caching activities, as seen in the following screenshot. However, this data will be lost from Spark History Server after the cache is evicted or when the job finishes. Therefore, Executor Storage Used can be used to do an analysis of a failed job run due to transient storage issues.

In this particular example, the data was evenly distributed among the executors. However, if you have a data skew (for, example only 1–2 executors out of 99 process the most amount of data, and as a result, your job runs out of disk space), the CloudWatch dashboard won’t accurately capture this scenario because the storage data is aggregated across all the executors for a job. For diagnosing issues at the individual executor level, we need to track per-executor-level metrics. We explore more advanced examples of how per-worker-level metrics can help you identify, mitigate, and resolve hard-to-find issues through EMR Serverless integration with Amazon Managed Service for Prometheus.

Conclusion

In this post, you learned how to effectively manage and optimize your EMR Serverless application using a single CloudWatch dashboard with enhanced EMR Serverless metrics. These metrics are available in all AWS Regions where EMR Serverless is available. For more details about this feature, refer to Job-level monitoring.


About the Authors

Kashif Khan is a Sr. Analytics Specialist Solutions Architect at AWS, specializing in big data services like Amazon EMR, AWS Lake Formation, AWS Glue, Amazon Athena, and Amazon DataZone. With over a decade of experience in the big data domain, he possesses extensive expertise in architecting scalable and robust solutions. His role involves providing architectural guidance and collaborating closely with customers to design tailored solutions using AWS analytics services to unlock the full potential of their data.

Veena Vasudevan is a Principal Partner Solutions Architect and Data & AI specialist at AWS. She helps customers and partners build highly optimized, scalable, and secure solutions; modernize their architectures; and migrate their big data, analytics, and AI/ML workloads to AWS.

Use Batch Processing Gateway to automate job management in multi-cluster Amazon EMR on EKS environments

Post Syndicated from Umair Nawaz original https://aws.amazon.com/blogs/big-data/use-batch-processing-gateway-to-automate-job-management-in-multi-cluster-amazon-emr-on-eks-environments/

AWS customers often process petabytes of data using Amazon EMR on EKS. In enterprise environments with diverse workloads or varying operational requirements, customers frequently choose a multi-cluster setup due to the following advantages:

  • Better resiliency and no single point of failure – If one cluster fails, other clusters can continue processing critical workloads, maintaining business continuity
  • Better security and isolation – Increased isolation between jobs enhances security and simplifies compliance
  • Better scalability – Distributing workloads across clusters enables horizontal scaling to handle peak demands
  • Performance benefits – Minimizing Kubernetes scheduling delays and network bandwidth contention improves job runtimes
  • Increased flexibility – You can enjoy straightforward experimentation and cost optimization through workload segregation to multiple clusters

However, one of the disadvantages of a multi-cluster setup is that there is no straightforward method to distribute workloads and support effective load balancing across multiple clusters. This post proposes a solution to this challenge by introducing the Batch Processing Gateway (BPG), a centralized gateway that automates job management and routing in multi-cluster environments.

Challenges with multi-cluster environments

In a multi-cluster environment, Spark jobs on Amazon EMR on EKS need to be submitted to different clusters from various clients. This architecture introduces several key challenges:

  • Endpoint management – Clients must maintain and update connections for each target cluster
  • Operational overhead – Managing multiple client connections individually increases the complexity and operational burden
  • Workload distribution – There is no built-in mechanism for job routing across multiple clusters, which impacts configuration, resource allocation, cost transparency, and resilience
  • Resilience and high availability – Without load balancing, the environment lacks fault tolerance and high availability

BPG addresses these challenges by providing a single point of submission for Spark jobs. BPG automates job routing to the appropriate EMR on EKS clusters, providing effective load balancing, simplified endpoint management, and improved resilience. The proposed solution is particularly beneficial for customers with multi-cluster Amazon EMR on EKS setups using the Spark Kubernetes Operator with or without Yunikorn scheduler.

However, although BPG offers significant benefits, it is currently designed to work only with Spark Kubernetes Operator. Additionally, BPG has not been tested with the Volcano scheduler, and the solution is not applicable in environments using native Amazon EMR on EKS APIs.

Solution overview

Martin Fowler describes a gateway as an object that encapsulates access to an external system or resource. In this case, the resource is the EMR on EKS clusters running Spark. A gateway acts as a single point to confront this resource. Any code or connection interacts with the interface of the gateway only. The gateway then translates the incoming API request into the API offered by the resource.
BPG is a gateway specifically designed to provide a seamless interface to Spark on Kubernetes. It’s a REST API service to abstract the underlying Spark on EKS clusters details from users. It runs in its own EKS cluster communicating to Kubernetes API servers of different EKS clusters. Spark users submit an application to BPG through clients, then BPG routes the application to one of the underlying EKS clusters.

The process for submitting Spark jobs using BPG for Amazon EMR on EKS is as follows:

  1. The user submits a job to BPG using a client.
  2. BPG parses the request, translates it into a custom resource definition (CRD), and submits the CRD to an EMR on EKS cluster according to predefined rules.
  3. The Spark Kubernetes Operator interprets the job specification and initiates the job on the cluster.
  4. The Kubernetes scheduler schedules and manages the run of the jobs.

The following figure illustrates the high-level details of BPG. You can read more about BPG in the GitHub README.

Image showing the high-level details of Batch Processing Gateway

The proposed solution involves implementing BPG for multiple underlying EMR on EKS clusters, which effectively resolves the drawbacks discussed earlier. The following diagram illustrates the details of the solution.

Image showing the end to end architecture of of Batch Processing Gateway

Source Code

You can find the code base in the AWS Samples and Batch Processing Gateway GitHub repository.

In the following sections, we walk through the steps to implement the solution.

Prerequisites

Before you deploy this solution, make sure the following prerequisites are in place:

Clone the repositories to your local machine

We assume that all repositories are cloned into the home directory (~/). All relative paths provided are based on this assumption. If you have cloned the repositories to a different location, adjust the paths accordingly.

  1. Clone the BPG on EMR on EKS GitHub repo with the following command:
cd ~/
git clone [email protected]:aws-samples/batch-processing-gateway-on-emr-on-eks.git

The BPG repository is currently under active development. To provide a stable deployment experience consistent with the provided instructions, we have pinned the repository to the stable commit hash aa3e5c8be973bee54ac700ada963667e5913c865.

Before cloning the repository, verify any security updates and adhere to your organization’s security practices.

  1. Clone the BPG GitHub repo with the following command:
git clone [email protected]:apple/batch-processing-gateway.git
cd batch-processing-gateway
git checkout aa3e5c8be973bee54ac700ada963667e5913c865

Create two EMR on EKS clusters

The creation of EMR on EKS clusters is not the primary focus of this post. For comprehensive instructions, refer to Running Spark jobs with the Spark operator. However, for your convenience, we have included the steps for setting up the EMR on EKS virtual clusters named spark-cluster-a-v and spark-cluster-b-v in the GitHub repo. Follow these steps to create the clusters.

After successfully completing the steps, you should have two EMR on EKS virtual clusters named spark-cluster-a-v and spark-cluster-b-v running on the EKS clusters spark-cluster-a and spark-cluster-b, respectively.

To verify the successful creation of the clusters, open the Amazon EMR console and choose Virtual clusters under EMR on EKS in the navigation pane.

Image showing the Amazon EMR on EKS setup

Set up BPG on Amazon EKS

To set up BPG on Amazon EKS, complete the following steps:

  1. Change to the appropriate directory:
cd ~/batch-processing-gateway-on-emr-on-eks/bpg/
  1. Set up the AWS Region:
export AWS_REGION="<AWS_REGION>"
  1. Create a key pair. Make sure you follow your organization’s best practices for key pair management.
aws ec2 create-key-pair \
--region "$AWS_REGION" \
--key-name ekskp \
--key-type ed25519 \
--key-format pem \
--query "KeyMaterial" \
--output text > ekskp.pem
chmod 400 ekskp.pem
ssh-keygen -y -f ekskp.pem > eks_publickey.pem
chmod 400 eks_publickey.pem

Now you’re ready to create the EKS cluster.

By default, eksctl creates an EKS cluster in dedicated virtual private clouds (VPCs). To avoid reaching the default soft limit on the number of VPCs in an account, we use the --vpc-public-subnets parameter to create clusters in an existing VPC. For this post, we use the default VPC for deploying the solution. Modify the following code to deploy the solution in the appropriate VPC in accordance with your organization’s best practices. For official guidance, refer to Create a VPC.

  1. Get the public subnets for your VPC:
export DEFAULT_FOR_AZ_SUBNET=$(aws ec2 describe-subnets --region "$AWS_REGION" --filters "Name=default-for-az,Values=true" --query "Subnets[?AvailabilityZone != 'us-east-1e'].SubnetId" | jq -r '. | map(tostring) | join(",")')
  1. Create the cluster:
eksctl create cluster \
--name bpg-cluster \
--region "$AWS_REGION" \
--vpc-public-subnets "$DEFAULT_FOR_AZ_SUBNET" \
--with-oidc \
--ssh-access \
--ssh-public-key eks_publickey.pem \
--instance-types=m5.xlarge \
--managed
  1. On the Amazon EKS console, choose Clusters in the navigation pane and check for the successful provisioning of the bpg-cluster

Image showing the Amazon EKS based BPG cluster setup

In the next steps, we make the following changes to the existing batch-processing-gateway code base:

For your convenience, we have provided the updated files in the batch-processing-gateway-on-emr-on-eks repository. You can copy these files into the batch-processing-gateway repository.

  1. Replace POM xml file:
cp ~/batch-processing-gateway-on-emr-on-eks/bpg/pom.xml ~/batch-processing-gateway/pom.xml
  1. Replace DAO java file:
cp ~/batch-processing-gateway-on-emr-on-eks/bpg/LogDao.java ~/batch-processing-gateway/src/main/java/com/apple/spark/core/LogDao.java
  1. Replace the Dockerfile:
cp ~/batch-processing-gateway-on-emr-on-eks/bpg/Dockerfile ~/batch-processing-gateway/Dockerfile

Now you’re ready to build your Docker image.

  1. Create a private Amazon Elastic Container Registry (Amazon ECR) repository:
aws ecr create-repository --repository-name bpg --region "$AWS_REGION"
  1. Get the AWS account ID:
export AWS_ACCOUNT_ID=$(aws sts get-caller-identity --query "Account" --output text)

  1. Authenticate Docker to your ECR registry:
aws ecr get-login-password --region "$AWS_REGION" | docker login --username AWS --password-stdin "$AWS_ACCOUNT_ID".dkr.ecr."$AWS_REGION".amazonaws.com
  1. Build your Docker image:
cd ~/batch-processing-gateway/
docker build \
--platform linux/amd64 \
--build-arg VERSION="1.0.0" \
--build-arg BUILD_TIME=$(date -u +"%Y-%m-%dT%H:%M:%SZ") \
--build-arg GIT_COMMIT=$(git rev-parse HEAD) \
--progress=plain \
--no-cache \
-t bpg:1.0.0 .
  1. Tag your image:
docker tag bpg:1.0.0 "$AWS_ACCOUNT_ID".dkr.ecr."$AWS_REGION".amazonaws.com/bpg:1.0.0
  1. Push the image to your ECR repository:
docker push "$AWS_ACCOUNT_ID".dkr.ecr."$AWS_REGION".amazonaws.com/bpg:1.0.0

The ImagePullPolicy in the batch-processing-gateway GitHub repo is set to IfNotPresent. Update the image tag in case you need to update the image.

  1. To verify the successful creation and upload of the Docker image, open the Amazon ECR console, choose Repositories under Private registry in the navigation pane, and locate the bpg repository:

Image showing the Amazon ECR setup

Set up an Amazon Aurora MySQL database

Complete the following steps to set up an Amazon Aurora MySQL-Compatible Edition database:

  1. List all default subnets for the given Availability Zone in a specific format:
DEFAULT_FOR_AZ_SUBNET_RFMT=$(aws ec2 describe-subnets --region "$AWS_REGION" --filters "Name=default-for-az,Values=true" --query "Subnets[*].SubnetId" | jq -c '.')
  1. Create a subnet group. Refer to create-db-subnet-group for more details.
aws rds create-db-subnet-group \
--db-subnet-group-name bpg-rds-subnetgroup \
--db-subnet-group-description "BPG Subnet Group for RDS" \
--subnet-ids "$DEFAULT_FOR_AZ_SUBNET_RFMT" \
--region "$AWS_REGION"
  1. List the default VPC:
export DEFAULT_VPC=$(aws ec2 describe-vpcs --region "$AWS_REGION" --filters "Name=isDefault,Values=true" --query "Vpcs[0].VpcId" --output text)
  1. Create a security group:
aws ec2 create-security-group \
--group-name bpg-rds-securitygroup \
--description "BPG Security Group for RDS" \
--vpc-id "$DEFAULT_VPC" \
--region "$AWS_REGION"
  1. List the bpg-rds-securitygroup security group ID:
export BPG_RDS_SG=$(aws ec2 describe-security-groups --filters "Name=group-name,Values=bpg-rds-securitygroup" --query "SecurityGroups[*].GroupId" --output text)
  1. Create the Aurora DB Regional cluster. Refer to create-db-cluster for more details.
aws rds create-db-cluster \
--database-name bpg \
--db-cluster-identifier bpg \
--engine aurora-mysql \
--engine-version 8.0.mysql_aurora.3.06.1 \
--master-username admin \
--manage-master-user-password \
--db-subnet-group-name bpg-rds-subnetgroup \
--vpc-security-group-ids "$BPG_RDS_SG" \
--region "$AWS_REGION"
  1. Create a DB Writer instance in the cluster. Refer to create-db-instance for more details.
aws rds create-db-instance \
--db-instance-identifier bpg \
--db-cluster-identifier bpg \
--db-instance-class db.r5.large \
--engine aurora-mysql \
--region "$AWS_REGION"

  1. To verify the successful creation of the RDS Regional cluster and Writer instance, on the Amazon RDS console, choose Databases in the navigation pane and check for the bpg database.

Image showing the RDS setup

Set up network connectivity

Security groups for EKS clusters are typically associated with the nodes and the control plane (if using managed nodes). In this section, we configure the networking to allow the node security group of the bpg-cluster to communicate with spark-cluster-a, spark-cluster-b, and the bpg Aurora RDS cluster.

  1. Identify the security groups of bpg-cluster, spark-cluster-a, spark-cluster-b, and the bpg Aurora RDS cluster:
# Identify Node Security Group of the bpg-cluster
BPG_CLUSTER_NODEGROUP_SG=$(aws ec2 describe-instances \
--filters Name=tag:eks:cluster-name,Values=bpg-cluster \
--query "Reservations[*].Instances[*].SecurityGroups[?contains(GroupName, 'eks-cluster-sg-bpg-cluster-')].GroupId" \
--region "$AWS_REGION" \
--output text | uniq)

# Identify Cluster security group of spark-cluster-a and spark-cluster-b
SPARK_A_CLUSTER_SG=$(aws eks describe-cluster --name spark-cluster-a --query "cluster.resourcesVpcConfig.clusterSecurityGroupId" --output text)
SPARK_B_CLUSTER_SG=$(aws eks describe-cluster --name spark-cluster-b --query "cluster.resourcesVpcConfig.clusterSecurityGroupId" --output text)

# Identify Cluster security group of bpg Aurora RDS cluster Writer Instance
BPG_RDS_WRITER_SG=$(aws ec2 describe-security-groups --filters "Name=group-name,Values=bpg-rds-securitygroup" --query "SecurityGroups[*].GroupId" --output text)

  1. Allow the node security group of the bpg-cluster to communicate with spark-cluster-a, spark-cluster-b, and the bpg Aurora RDS cluster:
# spark-cluster-a
aws ec2 authorize-security-group-ingress --group-id "$SPARK_A_CLUSTER_SG" --protocol tcp --port 443 --source-group "$BPG_CLUSTER_NODEGROUP_SG"

# spark-cluster-b
aws ec2 authorize-security-group-ingress --group-id "$SPARK_B_CLUSTER_SG" --protocol tcp --port 443 --source-group "$BPG_CLUSTER_NODEGROUP_SG"

# bpg-rds
aws ec2 authorize-security-group-ingress --group-id "$BPG_RDS_WRITER_SG" --protocol tcp --port 3306 --source-group "$BPG_CLUSTER_NODEGROUP_SG"

Deploy BPG

We deploy BPG for weight-based cluster selection. spark-cluster-a-v and spark-cluster-b-v are configured with a queue named dev and weight=50. We expect statistically equal distribution of jobs between the two clusters. For more information, refer to Weight Based Cluster Selection.

  1. Get the bpg-cluster context:
BPG_CLUSTER_CONTEXT=$(kubectl config view --output=json | jq -r '.contexts[] | select(.name | contains("bpg-cluster")) | .name')
kubectl config use-context "$BPG_CLUSTER_CONTEXT"

  1. Create a Kubernetes namespace for BPG:
kubectl create namespace bpg

The helm chart for BPG requires a values.yaml file. This file includes various key-value pairs for each EMR on EKS clusters, EKS cluster, and Aurora cluster. Manually updating the values.yaml file can be cumbersome. To simplify this process, we’ve automated the creation of the values.yaml file.

  1. Run the following script to generate the values.yaml file:
cd ~/batch-processing-gateway-on-emr-on-eks/bpg
chmod 755 create-bpg-values-yaml.sh
./create-bpg-values-yaml.sh
  1. Use the following code to deploy the helm chart. Make sure the tag value in both values.template.yaml and values.yaml matches the Docker image tag specified earlier.
cp ~/batch-processing-gateway/helm/batch-processing-gateway/values.yaml ~/batch-processing-gateway/helm/batch-processing-gateway/values.yaml.$(date +'%Y%m%d%H%M%S') \
&& cp ~/batch-processing-gateway-on-emr-on-eks/bpg/values.yaml ~/batch-processing-gateway/helm/batch-processing-gateway/values.yaml \
&& cd ~/batch-processing-gateway/helm/batch-processing-gateway/

kubectl config use-context "$BPG_CLUSTER_CONTEXT"

helm install batch-processing-gateway . --values values.yaml -n bpg

  1. Verify the deployment by listing the pods and viewing the pod logs:
kubectl get pods --namespace bpg
kubectl logs <BPG-PODNAME> --namespace bpg
  1. Exec into the BPG pod and verify the health check:
kubectl exec -it <BPG-PODNAME> -n bpg -- bash 
curl -u admin:admin localhost:8080/skatev2/healthcheck/status

We get the following output:

{"status":"OK"}

BPG is successfully deployed on the EKS cluster.

Test the solution

To test the solution, you can submit multiple Spark jobs by running the following sample code multiple times. The code submits the SparkPi Spark job to the BPG, which in turn submits the jobs to the EMR on EKS cluster based on the set parameters.

  1. Set the kubectl context to the bpg cluster:
kubectl config get-contexts | awk 'NR==1 || /bpg-cluster/'
kubectl config use-context "<CONTEXT_NAME>"
  1. Identify the bpg pod name:
kubectl get pods --namespace bpg
  1. Exec into the bpg pod:

kubectl exec -it "<BPG-PODNAME>" -n bpg -- bash

  1. Submit multiple Spark jobs using the curl. Run the below curl command to submit jobs to spark-cluster-a and spark-cluster-b:
curl -u user:pass localhost:8080/skatev2/spark -i -X POST \
-H 'Content-Type: application/json' \
-d '{
"applicationName": "SparkPiDemo",
"queue": "dev",
"sparkVersion": "3.5.0",
"mainApplicationFile": "local:///usr/lib/spark/examples/jars/spark-examples.jar",
"mainClass":"org.apache.spark.examples.SparkPi",
"driver": {
"cores": 1,
"memory": "2g",
"serviceAccount": "emr-containers-sa-spark",
"labels":{
"version": "3.5.0"
}
},
"executor": {
"instances": 1,
"cores": 1,
"memory": "2g",
"labels":{
"version": "3.5.0"
}
}
}'

After each submission, BPG will inform you of the cluster to which the job was submitted. For example:

HTTP/1.1 200 OK
Date: Sat, 10 Aug 2024 16:17:15 GMT
Content-Type: application/json
Content-Length: 67
{"submissionId":"spark-cluster-a-f72a7ddcfde14f4390194d4027c1e1d6"}
{"submissionId":"spark-cluster-a-d1b359190c7646fa9d704122fbf8c580"}
{"submissionId":"spark-cluster-b-7b61d5d512bb4adeb1dd8a9977d605df"}
  1. Verify that the jobs are running in the EMR cluster spark-cluster-a and spark-cluster-b:
kubectl config get-contexts | awk 'NR==1 || /spark-cluster-(a|b)/'
kubectl get pods -n spark-operator --context "<CONTEXT_NAME>"

You can view the Spark Driver logs to find the value of Pi as shown below:

kubectl logs <SPARK-DRIVER-POD-NAME> --namespace spark-operator --context "<CONTEXT_NAME>"

After successful completion of the job, you should be able to see the below message in the logs:

Pi is roughly 3.1452757263786317

We have successfully tested the weight-based routing of Spark jobs across multiple clusters.

Clean up

To clean up your resources, complete the following steps:

  1. Delete the EMR on EKS virtual cluster:
VIRTUAL_CLUSTER_ID=$(aws emr-containers list-virtual-clusters --region="$AWS_REGION" --query "virtualClusters[?name=='spark-cluster-a-v' && state=='RUNNING'].id" --output text)
aws emr-containers delete-virtual-cluster --region="$AWS_REGION" --id "$VIRTUAL_CLUSTER_ID"
VIRTUAL_CLUSTER_ID=$(aws emr-containers list-virtual-clusters --region="$AWS_REGION" --query "virtualClusters[?name=='spark-cluster-b-v' && state=='RUNNING'].id" --output text)
aws emr-containers delete-virtual-cluster --region="$AWS_REGION" --id "$VIRTUAL_CLUSTER_ID"

  1. Delete the AWS Identity and Access Management (IAM) role:
aws iam delete-role-policy --role-name sparkjobrole --policy-name EMR-Spark-Job-Execution
aws iam delete-role --role-name sparkjobrole

  1. Delete the RDS DB instance and DB cluster:
aws rds delete-db-instance \
--db-instance-identifier bpg \
--skip-final-snapshot

aws rds delete-db-cluster \
--db-cluster-identifier bpg \
--skip-final-snapshot

  1. Delete the bpg-rds-securitygroup security group and bpg-rds-subnetgroup subnet group:
BPG_SG=$(aws ec2 describe-security-groups --filters "Name=group-name,Values=bpg-rds-securitygroup" --query "SecurityGroups[*].GroupId" --output text)
aws ec2 delete-security-group --group-id "$BPG_SG"
aws rds delete-db-subnet-group --db-subnet-group-name bpg-rds-subnetgroup

  1. Delete the EKS clusters:
eksctl delete cluster --region="$AWS_REGION" --name=bpg-cluster
eksctl delete cluster --region="$AWS_REGION" --name=spark-cluster-a
eksctl delete cluster --region="$AWS_REGION" --name=spark-cluster-b

  1. Delete bpg ECR repository:
aws ecr delete-repository --repository-name bpg --region="$AWS_REGION" --force

  1. Delete the key pairs:
aws ec2 delete-key-pair --key-name ekskp
aws ec2 delete-key-pair --key-name emrkp

Conclusion

In this post, we explored the challenges associated with managing workloads on EMR on EKS cluster and demonstrated the advantages of adopting a multi-cluster deployment pattern. We introduced Batch Processing Gateway (BPG) as a solution to these challenges, showcasing how it simplifies job management, enhances resilience, and improves horizontal scalability in multi-cluster environments. By implementing BPG, we illustrated the practical application of the gateway architecture pattern for submitting Spark jobs on Amazon EMR on EKS. This post provides a comprehensive understanding of the problem, the benefits of the gateway architecture, and the steps to implement BPG effectively.

We encourage you to evaluate your existing Spark on Amazon EMR on EKS implementation and consider adopting this solution. It allows users to submit, examine, and delete Spark applications on Kubernetes with intuitive API calls, without needing to worry about the underlying complexities.

For this post, we focused on the implementation details of the BPG. As a next step, you can explore integrating BPG with clients such as Apache Airflow, Amazon Managed Workflows for Apache Airflow (Amazon MWAA), or Jupyter notebooks. BPG works well with the Apache Yunikorn scheduler. You can also explore integrating BPG to use Yunikorn queues for job submission.


About the Authors

Image of Author: Umair NawazUmair Nawaz is a Senior DevOps Architect at Amazon Web Services. He works on building secure architectures and advises enterprises on agile software delivery. He is motivated to solve problems strategically by utilizing modern technologies.

Image of Author: Ravikiran RaoRavikiran Rao is a Data Architect at Amazon Web Services and is passionate about solving complex data challenges for various customers. Outside of work, he is a theater enthusiast and amateur tennis player.

Image of Author: Sri PotluriSri Potluri is a Cloud Infrastructure Architect at Amazon Web Services. He is passionate about solving complex problems and delivering well-structured solutions for diverse customers. His expertise spans across a range of cloud technologies, ensuring scalable and reliable infrastructure tailored to each project’s unique challenges.

Image of Author: Suvojit DasguptaSuvojit Dasgupta is a Principal Data Architect at Amazon Web Services. He leads a team of skilled engineers in designing and building scalable data solutions for AWS customers. He specializes in developing and implementing innovative data architectures to address complex business challenges.

How CFM built a well-governed and scalable data-engineering platform using Amazon EMR for financial features generation

Post Syndicated from Julien Lafaye original https://aws.amazon.com/blogs/big-data/how-cfm-built-a-well-governed-and-scalable-data-engineering-platform-using-amazon-emr-for-financial-features-generation/

This post is co-written with Julien Lafaye from CFM.

Capital Fund Management (CFM) is an alternative investment management company based in Paris with staff in New York City and London. CFM takes a scientific approach to finance, using quantitative and systematic techniques to develop the best investment strategies. Over the years, CFM has received many awards for their flagship product Stratus, a multi-strategy investment program that delivers decorrelated returns through a diversified investment approach while seeking a risk profile that is less volatile than traditional market indexes. It was first opened to investors in 1995. CFM assets under management are now $13 billion.

A traditional approach to systematic investing involves analysis of historical trends in asset prices to anticipate future price fluctuations and make investment decisions. Over the years, the investment industry has grown in such a way that relying on historical prices alone is not enough to remain competitive: traditional systematic strategies progressively became public and inefficient, while the number of actors grew, making slices of the pie smaller—a phenomenon known as alpha decay. In recent years, driven by the commoditization of data storage and processing solutions, the industry has seen a growing number of systematic investment management firms switch to alternative data sources to drive their investment decisions. Publicly documented examples include the usage of satellite imagery of mall parking lots to estimate trends in consumer behavior and its impact on stock prices. Using social network data has also often been cited as a potential source of data to improve short-term investment decisions. To remain at the forefront of quantitative investing, CFM has put in place a large-scale data acquisition strategy.

As the CFM Data team, we constantly monitor new data sources and vendors to continue to innovate. The speed at which we can trial datasets and determine whether they are useful to our business is a key factor of success. Trials are short projects usually taking up to a several months; the output of a trial is a buy (or not-buy) decision if we detect information in the dataset that can help us in our investment process. Unfortunately, because datasets come in all shapes and sizes, planning our hardware and software requirements several months ahead has been very challenging. Some datasets require large or specific compute capabilities that we can’t afford to buy if the trial is a failure. The AWS pay-as-you-go model and the constant pace of innovation in data processing technologies enable CFM to maintain agility and facilitate a steady cadence of trials and experimentation.

In this post, we share how we built a well-governed and scalable data engineering platform using Amazon EMR for financial features generation.

AWS as a key enabler of CFM’s business strategy

We have identified the following as key enablers of this data strategy:

  • Managed services – AWS managed services reduce the setup cost of complex data technologies, such as Apache Spark.
  • Elasticity – Compute and storage elasticity removes the burden of having to plan and size hardware procurement. This allows us to be more focused on the business and more agile in our data acquisition strategy.
  • Governance – At CFM, our Data teams are split into autonomous teams that can use different technologies based on their requirements and skills. Each team is the sole owner of its AWS account. To share data to our internal consumers, we use AWS Lake Formation with LF-Tags to streamline the process of managing access rights across the organization.

Data integration workflow

A typical data integration process consists of ingestion, analysis, and production phases.

CFM usually negotiates with vendors a download method that is convenient for both parties. We see a lot of possibilities for exchanging data (HTTPS, FPT, SFPT), but we’re seeing a growing number of vendors standardizing around Amazon Simple Storage Service (Amazon S3).

 CFM data scientists then look up the data and build features that can be used in our trading models. The bulk of our data scientists are heavy users of Jupyter Notebook. Jupyter notebooks are interactive computing environments that allow users to create and share documents containing live code, equations, visualizations, and narrative text. They provide a web-based interface where users can write and run code in different programming languages, such as Python, R, or Julia. Notebooks are organized into cells, which can be run independently, facilitating the iterative development and exploration of data analysis and computational workflows.

We invested a lot in polishing our Jupyter stack (see, for example, the open source project Jupytext, which was initiated by a former CFM employee), and we are proud of the level of integration with our ecosystem that we have reached. Although we explored the option of using AWS managed notebooks to streamline the provisioning process, we have decided to continue hosting these components on our on-premises infrastructure for the current timeline. CFM internal users appreciate the existing development environment and switching to an AWS managed environment would imply a change to their habits, and a temporary drop in productivity.

Exploration of small datasets is entirely feasible within this Jupyter environment, but for large datasets, we have identified Spark as the go-to solution. We could have deployed Spark clusters in our data centers, but we have found that Amazon EMR considerably reduces the time to deploy said clusters and provides many interesting features, such as ARM support through AWS Graviton processors, auto scaling capabilities, and the ability to provision transient clusters.

 After a data scientist has written the feature, CFM deploys a script to the production environment that refreshes the feature as new data comes in. These scripts often run in a relatively short amount of time because they only require processing a small increment of data.

Interactive data exploration workflow

CFM’s data scientists’ preferred way of interacting with EMR clusters is through Jupyter notebooks. Having a long history of managing Jupyter notebooks on premises and customizing them, we opted to integrate EMR clusters into our existing stack. The user workflow is as follows:

  1. The user provisions an EMR cluster through the AWS Service Catalog and the AWS Management Console. Users can also use API calls to do this, but usually prefer using the Service Catalog interface. You can choose various instance types that include different combinations of CPU, memory, and storage, giving you the flexibility to choose the appropriate mix of resources for your applications.
  2. The user starts their Jupyter notebook instance and connects to the EMR cluster.
  3. The user interactively works on the data using the notebook.
  4. The user shuts down the cluster through the Service Catalog.

Solution overview

The connection between the notebook and the cluster is achieved by deploying the following open source components:

  • Apache Livy – This service that provides a REST interface to a Spark driver running on an EMR cluster.
  • Sparkmagic – This set of Jupyter magics provides a straightforward way to connect to the cluster and send PySpark code to the cluster through the Livy endpoint.
  • Sagemaker-studio-analytics-extension – This library provides a set of magics to integrate analytics services (such as Amazon EMR) into Jupyter notebooks. It is used to integrate Amazon SageMaker Studio notebooks and EMR clusters (for more details, see Create and manage Amazon EMR Clusters from SageMaker Studio to run interactive Spark and ML workloads – Part 1). Having the requirement to use our own notebooks, we initially didn’t benefit from this integration. To help us, the Amazon EMR service team made this library available on PyPI and guided us in setting it up. We use this library to facilitate the connection between the notebook and the cluster and to forward the user permissions to the clusters through runtime roles. These runtime roles are then used to access the data instead of instance profile roles assigned to the Amazon Elastic Compute Cloud (Amazon EC2) instances that are part of the cluster. This allows more fine-grained access control on our data.

The following diagram illustrates the solution architecture.

Set up Amazon EMR on an EC2 cluster with the GetClusterSessionCredentials API

A runtime role is an AWS Identity and Access Management (IAM) role that you can specify when you submit a job or query to an EMR cluster. The EMR get-cluster-session-credentials API uses a runtime role to authenticate on EMR nodes based on the IAM policies attached runtime role (we document the steps to enable for the Spark terminal; a similar approach can be expanded for Hive and Presto). This option is generally available in all AWS Regions and the recommended release to use is emr-6.9.0 or later.

Connect to Amazon EMR on the EC2 cluster from Jupyter Notebook with the GCSC API

Jupyter Notebook magic commands provide shortcuts and extra functionality to the notebooks in addition to what can be done with your kernel code. We use Jupyter magics to abstract the underlying connection from Jupyter to the EMR cluster; the analytics extension makes the connection through Livy using the GCSC API.

On your Jupyter instance, server, or notebook PySpark kernel, install the following extension, load the magics, and create a connection to the EMR cluster using your runtime role:

pip install sagemaker-studio-analytics-extension
%load_ext sagemaker_studio_analytics_extension.magics
%sm_analytics emr connect --cluster-id j-XXXXXYYYYY --auth-type Basic_Access --language python --emr-executiojn-role-arn

Production with Amazon EMR Serverless

CFM has implemented an architecture based on dozens of pipelines: data is ingested from data on Amazon S3 and transformed using Amazon EMR Serverless with Spark; resulting datasets are published back to Amazon S3.

Each pipeline runs as a separate EMR Serverless application to avoid resource contention between workloads. Individual IAM roles are assigned to each EMR Serverless application to apply least privilege access.

To control costs, CFM uses EMR Serverless automatic scaling combined with the maximum capacity feature (which defines the maximum total vCPU, memory, and disk capacity that can be consumed collectively by all the jobs running under this application). Finally, CFM uses an AWS Graviton architecture to optimize even more cost and performance (as highlighted in the screenshot below).

After some iterations, the user produces a final script that is put in production. For early deployments, we relied on Amazon EMR on EC2 to run those scripts. Based on user feedback, we iterated and investigated for opportunities to reduce cluster startup times. Cluster startups could take up to 8 minutes for a runtime requiring a fraction of that time, which impacted the user experience. Also, we wanted to reduce the operational overhead of starting and stopping EMR clusters.

Those are the reasons why we switched to EMR Serverless a few months after its initial release. This move was surprisingly straightforward because it didn’t require any tuning and worked instantly. The only drawback we have seen is the requirement to update AWS tools and libraries in our software stacks to incorporate all the EMR features (such as AWS Graviton); on the other hand, it led to reduced startup time, reduced costs, and better workload isolation.

At this stage, CFM data scientists can perform analytics and extract value from raw data. Resulting datasets are then published to our data mesh service across our organization to allow our scientists to work on prediction models. In the context of CFM, this requires a strong governance and security posture to apply fine-grained access control to this data. This data mesh approach allows CFM to have a clear view from an audit standpoint on dataset usage.

Data governance with Lake Formation

A data mesh on AWS is an architectural approach where data is treated as a product and owned by domain teams. Each team uses AWS services like Amazon S3, AWS Glue, AWS Lambda, and Amazon EMR to independently build and manage their data products, while tools like the AWS Glue Data Catalog enable discoverability. This decentralized approach promotes data autonomy, scalability, and collaboration across the organization:

  • Autonomy – At CFM, like at most companies, we have different teams with difference skillsets and different technology needs. Enabling teams to work autonomously was a key parameter in our decision to move to a decentralized model where each domain would live in its own AWS account. Another advantage was improved security, particularly the ability to contain the potential impact area in the event of credential leaks or account compromises. Lake Formation is key in enabling this kind of model because it streamlines the process of managing access rights across accounts. In the absence of Lake Formation, administrators would have to make sure that resource policies and user policies align to grant access to data: this is usually considered complex, error-prone, and hard to debug. Lake Formation makes this process a lot less complicated.
  • Scalability – There are no blockers that prevent other organization units from joining the data mesh structure, and we expect more teams to join the effort of refining and sharing their data assets.
  • Collaboration – Lake Formation provides a sound foundation for making data products discoverable by CFM internal consumers. On top of Lake Formation, we developed our own Data Catalog portal. It provides a user-friendly interface where users can discover datasets, read through the documentation, and download code snippets (see the following screenshot). The interface is tailor-made for our work habits.

Lake Formation documentation is extensive and provides a collection of ways to achieve a data governance pattern that fits every organization requirement. We made the following choices:

  • LF-Tags – We use LF-Tags instead of named resource permissioning. Tags are associated to resources, and personas are given the permission to access all resources with a certain tag. This makes scaling the process of managing rights straightforward. Also, this is an AWS recommended best practice.
  • Centralization – Databases and LF-Tags are managed in a centralized account, which is managed by a single team.
  • Decentralization of permissions management – Data producers are allowed to associate tags to the datasets they are responsible for. Administrators of consumer accounts can grant access to tagged resources.

Conclusions

In this post, we discussed how CFM built a well-governed and scalable data engineering platform for financial features generation.

Lake Formation provides a solid foundation for sharing datasets across accounts. It removes the operational complexity of managing complex cross-account access through IAM and resource policies. For now, we only use it to share assets created by data scientists, but plan to add new domains in the near future.

Lake Formation also seamlessly integrates with other analytics services like AWS Glue and Amazon Athena. The ability to provide a comprehensive and integrated suite of analytics tools to our users is a strong reason for adopting Lake Formation.

Last but not least, EMR Serverless reduced operational risk and complexity. EMR Serverless applications start in less than 60 seconds, whereas starting an EMR cluster on EC2 instances typically takes more than 5 minutes (as of this writing). The accumulation of those earned minutes effectively eliminated any further instances of missed delivery deadlines.

If you’re looking to streamline your data analytics workflow, simplify cross-account data sharing, and reduce operational overhead, consider using Lake Formation and EMR Serverless in your organization. Check out the AWS Big Data Blog and reach out to your AWS team to learn more about how AWS can help you use managed services to drive efficiency and unlock valuable insights from your data!


About the Authors

Julien Lafaye is a director at Capital Fund Management (CFM) where he is leading the implementation of a data platform on AWS. He is also heading a team of data scientists and software engineers in charge of delivering intraday features to feed CFM trading strategies. Before that, he was developing low latency solutions for transforming & disseminating financial market data. He holds a Phd in computer science and graduated from Ecole Polytechnique Paris. During his spare time, he enjoys cycling, running and tinkering with electronic gadgets and computers.

Matthieu Bonville is a Solutions Architect in AWS France working with Financial Services Industry (FSI) customers. He leverages his technical expertise and knowledge of the FSI domain to help customer architect effective technology solutions that address their business challenges.

Joel Farvault is Principal Specialist SA Analytics for AWS with 25 years’ experience working on enterprise architecture, data governance and analytics, mainly in the financial services industry. Joel has led data transformation projects on fraud analytics, claims automation, and Master Data Management. He leverages his experience to advise customers on their data strategy and technology foundations.

Attribute Amazon EMR on EC2 costs to your end-users

Post Syndicated from Raj Patel original https://aws.amazon.com/blogs/big-data/attribute-amazon-emr-on-ec2-costs-to-your-end-users/

Amazon EMR on EC2 is a managed service that makes it straightforward to run big data processing and analytics workloads on AWS. It simplifies the setup and management of popular open source frameworks like Apache Hadoop and Apache Spark, allowing you to focus on extracting insights from large datasets rather than the underlying infrastructure. With Amazon EMR, you can take advantage of the power of these big data tools to process, analyze, and gain valuable business intelligence from vast amounts of data.

Cost optimization is one of the pillars of the Well-Architected Framework. It focuses on avoiding unnecessary costs, selecting the most appropriate resource types, analyzing spend over time, and scaling in and out to meet business needs without overspending. An optimized workload maximizes the use of all available resources, delivers the desired outcome at the most cost-effective price point, and meets your functional needs.

The current Amazon EMR pricing page shows the estimated cost of the cluster. You can also use AWS Cost Explorer to get more detailed information about your costs. These views give you an overall picture of your Amazon EMR costs. However, you may need to attribute costs at the individual Spark job level. For example, you might want to know the usage cost in Amazon EMR for the finance business unit. Or, for chargeback purposes, you might need to aggregate the cost of Spark applications by functional area. After you have allocated costs to individual Spark jobs, this data can help you make informed decisions to optimize your costs. For instance, you could choose to restructure your applications to utilize fewer resources. Alternatively, you might opt to explore different pricing models like Amazon EMR on EKS or Amazon EMR Serverless.

In this post, we share a chargeback model that you can use to track and allocate the costs of Spark workloads running on Amazon EMR on EC2 clusters. We describe an approach that assigns Amazon EMR costs to different jobs, teams, or lines of business. You can use this feature to distribute costs across various business units. This can assist you in monitoring the return on investment for your Spark-based workloads.

Solution overview

The solution is designed to help you track the cost of your Spark applications running on EMR on EC2. It can help you identify cost optimizations and improve the cost-efficiency of your EMR clusters.

The proposed solution uses a scheduled AWS Lambda function that operates on a daily basis. The function captures usage and cost metrics, which are subsequently stored in Amazon Relational Database Service (Amazon RDS) tables. The data stored in the RDS tables is then queried to derive chargeback figures and generate reporting trends using Amazon QuickSight. The utilization of these AWS services incurs additional costs for implementing this solution. Alternatively, you can consider an approach that involves a cron-based agent script installed on your existing EMR cluster, if you want to avoid the use of additional AWS services and associated costs for building your chargeback solution. This script stores the relevant metrics in an Amazon Simple Storage Service (Amazon S3) bucket, and uses Python Jupyter notebooks to generate chargeback numbers based on the data files stored in Amazon S3, using AWS Glue tables.

The following diagram shows the current solution architecture.

Solution Architecture

The workflow consists of the following steps:

  1. A Lambda function gets the following parameters from Parameter Store, a capability of AWS Systems Manager:
    {
      "yarn_url": "http://dummy.compute-1.amazonaws.com:8088/ws/v1/cluster/apps",
      "tbl_applicationlogs_lz": "public.emr_applications_execution_log_lz",
      "tbl_applicationlogs": "public.emr_applications_execution_log",
      "tbl_emrcost": "public.emr_cluster_usage_cost",
      "tbl_emrinstance_usage": "public.emr_cluster_instances_usage",
      "emrcluster_id": "j-xxxxxxxxxx",
      "emrcluster_name": "EMR_Cost_Measure",
      "emrcluster_role": "dt-dna-shared",
      "emrcluster_linkedaccount": "xxxxxxxxxxx",
      "postgres_rds": {
        "host": "xxxxxxxxx.amazonaws.com",
        "dbname": "postgres",
        "user": "postgresadmin",
        "secretid": "postgressecretid"
      }
    }

  2. The Lambda function extracts Spark application run logs from the EMR cluster using the Resource Manager API. The following metrics are extracted as part of the process: vcore-seconds, memory MB-seconds, and storage GB-seconds.
  3. The Lambda function captures the daily cost of EMR clusters from Cost Explorer.
  4. The Lambda function also extracts EMR On-Demand and Spot Instance usage data using the Amazon Elastic Compute Cloud (Amazon EC2) Boto3 APIs.
  5. Lambda function loads these datasets into an RDS database.
  6. The cost of running a Spark application is determined by the amount of CPU resources it uses, compared to the total CPU usage of all Spark applications. This information is used to distribute the overall cost among different teams, business lines, or EMR queues.

The extraction process runs daily, extracting the previous day’s data and storing it in an Amazon RDS for PostgreSQL table. The historical data in the table needs to be purged based on your use case.

The solution is open source and available on GitHub.

You can use the AWS Cloud Development Kit (AWS CDK) to deploy the Lambda function, RDS for PostgreSQL data model tables, and a QuickSight dashboard to track EMR cluster cost at the job, team, or business unit level.

The following schema show the tables used in the solution which are queried by QuickSight to populate the dashboard.

  • emr_applications_execution_log_lz or public.emr_applications_execution_log – Storage for daily run metrics for all jobs run on the EMR cluster:
    • appdatecollect – Log collection date
    • app_id – Spark job run ID
    • app_name – Run name
    • queue – EMR queue in which job was run
    • job_state – Job running state
    • job_status – Job run final status (Succeeded or Failed)
    • starttime – Job start time
    • endtime – Job end time
    • runtime_seconds – Runtime in seconds
    • vcore_seconds – Consumed vCore CPU in seconds
    • memory_seconds – Memory consumed
    • running_containers – Containers used
    • rm_clusterid – EMR cluster ID
  • emr_cluster_usage_cost – Captures Amazon EMR and Amazon EC2 daily cost consumption from Cost Explorer and loads the data into the RDS table:
    • costdatecollect – Cost collection date
    • startdate – Cost start date
    • enddate – Cost end date
    • emr_unique_tag – EMR cluster associated tag
    • net_unblendedcost – Total unblended daily dollar cost
    • unblendedcost – Total unblended daily dollar cost
    • cost_type – Daily cost
    • service_name – AWS service for which the cost incurred (Amazon EMR and Amazon EC2)
    • emr_clusterid – EMR cluster ID
    • emr_clustername – EMR cluster name
    • loadtime – Table load date/time
  • emr_cluster_instances_usage – Captures the aggregated resource usage (vCores) and allocated resources for each EMR cluster node, and helps identify the idle time of the cluster:
    • instancedatecollect – Instance usage collect date
    • emr_instance_day_run_seconds – EMR instance active seconds in the day
    • emr_region – EMR cluster AWS Region
    • emr_clusterid – EMR cluster ID
    • emr_clustername – EMR cluster name
    • emr_cluster_fleet_type – EMR cluster fleet type
    • emr_node_type – Instance node type
    • emr_market – Market type (on-demand or provisioned)
    • emr_instance_type – Instance size
    • emr_ec2_instance_id – Corresponding EC2 instance ID
    • emr_ec2_status – Running status
    • emr_ec2_default_vcpus – Allocated vCPU
    • emr_ec2_memory – EC2 instance memory
    • emr_ec2_creation_datetime – EC2 instance creation date/time
    • emr_ec2_end_datetime – EC2 instance end date/time
    • emr_ec2_ready_datetime – EC2 instance ready date/time
    • loadtime – Table load date/time

Prerequisites

You must have the following prerequisites before implementing the solution:

  • An EMR on EC2 cluster.
  • The EMR cluster must have a unique tag value defined. You can assign the tag directly on the Amazon EMR console or using Tag Editor. The recommended tag key is cost-center along with a unique value for your EMR cluster. After you create and apply user-defined tags, it can take up to 24 hours for the tag keys to appear on your cost allocation tags page for activation
  • Activate the tag in AWS Billing. It takes about 24 hours to activate the tag if not done before. To activate the tag, follow these steps:
    • On the AWS Billing and Cost Management console, choose Cost allocation tags from navigation pane.
    • Select the tag key that you want to activate.
    • Choose Activate.
  • The Spark application’s name should follow the standardized naming convention. It consists of seven components separated by underscores: <business_unit>_<program>_<application>_<source>_<job_name>_<frequency>_<job_type>. These components are used to summarize the resource consumption and cost in the final report. For example: HR_PAYROLL_PS_PSPROD_TAXDUDUCTION_DLY_LD, FIN_CASHRECEIPT_GL_GLDB_MAIN_DLY_LD, or MKT_CAMPAIGN_CRM_CRMDB_TOPRATEDCAMPAIGN_DLY_LD. The application name must be supplied with the spark submit command using the --name parameter with the standardized naming convention. If any of these components don’t have a value, hardcode the values with the following suggested names:
    • frequency
    • job_type
    • Business_unit
  • The Lambda function should be able to connect to Cost Explorer, connect to the EMR cluster through the Resource Manager APIs, and load data into the RDS for PostgreSQL database. To do this, you need to configure the Lambda function as follows:
    • VPC configuration – The Lambda function should be able to access the EMR cluster, Cost Explorer, AWS Secrets Manager, and Parameter Store. If access is not in place already, you can do this by creating a virtual private cloud (VPC) that includes the EMR cluster and create VPC endpoint for Parameter Store and Secrets Manager and attach it to the VPC. Because there is no VPC endpoint available for Cost Explorer and in order to have Lambda connect to Cost Explorer, a private subnet and a route table are required to send VPC traffic to public NAT gateway. If your EMR cluster is in public subnet, you must create a private subnet including a custom route table and a public NAT gateway, which will allow the Cost Explorer connection to flow from the VPC private subnet. Refer to How do I set up a NAT gateway for a private subnet in Amazon VPC? for setup instructions and attach the newly created private subnet to the Lambda function explicitly.
    • IAM role – The Lambda function needs to have an AWS Identity and Access Management (IAM) role with the following permissions: AmazonEC2ReadOnlyAccess, AWSCostExplorerFullAccess, and AmazonRDSDataFullAccess. This role will be created automatically during AWS CDK stack deployment; you don’t need to set it up separately.
  • The AWS CDK should be installed on AWS Cloud9 (preferred) or another development environment such as VSCode or Pycharm. For more information, refer to Prerequisites.
  • The RDS for PostgreSQL database (v10 or higher) credentials should be stored in Secrets Manager. For more information, refer to Storing database credentials in AWS Secrets Manager.

Create RDS tables

Create the data model tables mentioned in emr-cost-rds-tables-ddl.sql by logging in to postgres rds manually into the public schema.

Use DBeaver or any compatible SQL clients to connect to the RDS instance and validate the tables have been created.

Deploy AWS CDK stacks

Complete the steps in this section to deploy the following resources using the AWS CDK:

  • Parameter Store to store required parameter values
  • IAM role for the Lambda function to help connect to Amazon EMR and underlying EC2 instances, Cost Explorer, CloudWatch, and Parameter Store
  • Lambda function
  1. Clone the GitHub repo:
    git clone [email protected]:aws-samples/attribute-amazon-emr-costs-to-your-end-users.git

  2. Update the following the environment parameters in cdk.context.json (this file can be found in the main directory):
    1. yarn_urlYARN ResourceManager URL to read job run logs and metrics. This URL should be accessible within the VPC where Lambda would be deployed.
    2. tbl_applicationlogs_lz – RDS temp table to store EMR application run logs.
    3. tbl_applicationlogs – RDS table to store EMR application run logs.
    4. tbl_emrcost – RDS table to capture daily EMR cluster usage cost.
    5. tbl_emrinstance_usage – RDS table to store EMR cluster instance usage info.
    6. emrcluster_id – EMR cluster instance ID.
    7. emrcluster_name – EMR cluster name.
    8. emrcluster_tag – Tag key assigned to EMR cluster.
    9. emrcluster_tag_value – Unique value for EMR cluster tag.
    10. emrcluster_role – Service role for Amazon EMR (EMR role).
    11. emrcluster_linkedaccount – Account ID under which the EMR cluster is running.
    12. postgres_rds – RDS for PostgreSQL connection details.
    13. vpc_id – VPC ID in which the EMR cluster is configured and the cost metering Lambda function would be deployed.
    14. vpc_subnets – Comma-separated private subnets ID associated with the VPC.
    15. sg_id – EMR security group ID.

The following is a sample cdk.context.json file after being populated with the parameters:

{
  "yarn_url": "http://dummy.compute-1.amazonaws.com:8088/ws/v1/cluster/apps",
  "tbl_applicationlogs_lz": "public.emr_applications_execution_log_lz",
  "tbl_applicationlogs": "public.emr_applications_execution_log",
  "tbl_emrcost": "public.emr_cluster_usage_cost",
  "tbl_emrinstance_usage": "public.emr_cluster_instances_usage",
  "emrcluster_id": "j-xxxxxxxxxx",
  "emrcluster_name": "EMRClusterName",
  "emrcluster_tag": "EMRClusterTag",
  "emrcluster_tag_value": "EMRClusterUniqueTagValue",
  "emrcluster_role": "EMRClusterServiceRole",
  "emrcluster_linkedaccount": "xxxxxxxxxxx",
  "postgres_rds": {
    "host": "xxxxxxxxx.amazonaws.com",
    "dbname": "dbname",
    "user": "username",
    "secretid": "DatabaseUserSecretID"
  },
  "vpc_id": "xxxxxxxxx",
  "vpc_subnets": "subnet-xxxxxxxxxxx",
  "sg_id": "xxxxxxxxxx"
}

You can choose to deploy the AWS CDK stack using AWS Cloud9 or any other development environment according to your needs. For instructions to set up AWS Cloud9, refer to Getting started: basic tutorials for AWS Cloud9.

  1. Go to AWS Cloud9 and choose File and Upload local files upload the project folder.
  2. Deploy the AWS CDK stack with the following code:
    cd attribute-amazon-emr-costs-to-your-end-users/
    pip install -r requirements.txt
    cdk deploy –-all

The deployed Lambda function requires two external libraries: psycopg2 and requests. The corresponding layer needs to be created and assigned to the Lambda function. For instructions to create a Lambda layer for the requests module, refer to Step-by-Step Guide to Creating an AWS Lambda Function Layer.

Creation of the psycopg2 package and layer is tied to the Python runtime version of the Lambda function. Provided that the Lambda function uses the Python 3.9 runtime, complete the following steps to create the corresponding layer package for peycopog2:

  1. Download psycopg2_binary-2.9.9-cp39-cp39-manylinux_2_17_x86_64.manylinux2014_x86_64.whl from https://pypi.org/project/psycopg2-binary/#files.
  2. Unzip and move the contents to a directory named python:
    zip ‘python’ directory

  3. Create a Lambda layer for psycopg2 using the zip file.
  4. Assign the layer to the Lambda function by choosing Add a layer in the deployed function properties.
  5. Validate the AWS CDK deployment.

Your Lambda function details should look similar to the following screenshot.

Lambda Function Screenshot

On the Systems Manager console, validate the Parameter Store content for actual values.

The IAM role details should look similar to the following code, which allows the Lambda function access to Amazon EMR and underlying EC2 instances, Cost Explorer, CloudWatch, Secrets Manager, and Parameter Store:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Action": [
        "ce:GetCostAndUsage",
        "ce:ListCostAllocationTags",
        "ec2:AttachNetworkInterface",
        "ec2:CreateNetworkInterface",
        "ec2:DeleteNetworkInterface",
        "ec2:DescribeInstanceTypes",
        "ec2:DescribeInstances",
        "ec2:DescribeNetworkInterfaces",
        "elasticmapreduce:Describe*",
        "elasticmapreduce:List*",
        "ssm:Describe*",
        "ssm:Get*",
        "ssm:List*"
      ],
      "Resource": "*",
      "Effect": "Allow"
    },
    {
      "Action": [
        "logs:CreateLogGroup",
        "logs:CreateLogStream",
        "logs:DescribeLogStreams",
        "logs:PutLogEvents"
      ],
      "Resource": "arn:aws:logs:*:*:*",
      "Effect": "Allow"
    },
    {
      "Action": "secretsmanager:GetSecretValue",
      "Resource": "arn:aws:secretsmanager:*:*:*",
      "Effect": "Allow"
    }
  ]
}

Test the solution

To test the solution, you can run a Spark job that combines multiple files in the EMR cluster, and you can do this by creating separate steps within the cluster. Refer to Optimize Amazon EMR costs for legacy and Spark workloads for more details on how to add the jobs as steps to EMR cluster.

  1. Use the following sample command to submit the Spark job (emr_union_job.py).
    It takes in three arguments:

    1. <input_full_path> – The Amazon S3 location of the data file that is read in by the Spark job. The path should not be changed. The input_full_path is s3://aws-blogs-artifacts-public/artifacts/BDB-2997/sample-data/input/part-00000-a0885743-e0cb-48b1-bc2b-05eb748ab898-c000.snappy.parquet
    2. <output_path> – The S3 folder where the results are written to.
    3. <number of copies to be unioned> – By changing the input to the Spark job, you can make sure the job runs for different amounts of time and also change the number of Spot nodes used.
spark-submit --deploy-mode cluster --name HR_PAYROLL_PS_PSPROD_TAXDUDUCTION_DLY_LD s3://aws-blogs-artifacts-public/artifacts/BDB-2997/scripts/emr_union_job.py s3://aws-blogs-artifacts-public/artifacts/BDB-2997/sample-data/input/part-00000-a0885743-e0cb-48b1-bc2b-05eb748ab898-c000.snappy.parquet s3://<output_bucket>/<output_path>/ 6

spark-submit --deploy-mode cluster --name FIN_CASHRECEIPT_GL_GLDB_MAIN_DLY_LD s3://aws-blogs-artifacts-public/artifacts/BDB-2997/scripts/emr_union_job.py s3://aws-blogs-artifacts-public/artifacts/BDB-2997/sample-data/input/part-00000-a0885743-e0cb-48b1-bc2b-05eb748ab898-c000.snappy.parquet s3://<output_bucket>/<output_path>/ 12

The following screenshot shows the log of the steps run on the Amazon EMR console.

EMR Steps Execution

  1. Run the deployed Lambda function from the Lambda console. This loads the daily application log, EMR dollar usage, and EMR instance usage details into their respective RDS tables.

The following screenshot of the Amazon RDS query editor shows the results for public.emr_applications_execution_log.

public.emr_applications_execution_log

The following screenshot shows the results for public.emr_cluster_usage_cost.

public.emr_cluster_usage_cost

The following screenshot shows the results for public.emr_cluster_instances_usage.

public.emr_cluster_instances_usage

Cost can be calculated using the preceding three tables based on your requirements. In the following SQL query, you calculate the cost based on relative usage of all applications in a day. You first identify the total vcore-seconds CPU consumed in a day and then find out the percentage share of an application. This drives the cost based on overall cluster cost in a day.

Consider the following example scenario, where 10 applications ran on the cluster for a given day. You would use the following sequence of steps to calculate the chargeback cost:

  1. Calculate the relative percentage usage of each application (consumed vcore-seconds CPU by app/total vcore-seconds CPU consumed).
  2. Now you have the relative resource consumption of each application, distribute the cluster cost to each application. Let’s assume that the total EMR cluster cost for that date is $400.
app_id app_name runtime_seconds vcore_seconds % Relative Usage Amazon EMR Cost ($)
application_00001 app1 10 120 5% 19.83
application_00002 app2 5 60 2% 9.91
application_00003 app3 4 45 2% 7.43
application_00004 app4 70 840 35% 138.79
application_00005 app5 21 300 12% 49.57
application_00006 app6 4 48 2% 7.93
application_00007 app7 12 150 6% 24.78
application_00008 app8 52 620 26% 102.44
application_00009 app9 12 130 5% 21.48
application_00010 app10 9 108 4% 17.84

A sample chargeback cost calculation SQL query is available on the GitHub repo.

You can use the SQL query to create a report dashboard to plot multiple charts for the insights. The following are two examples created using QuickSight.

The following is a daily bar chart.

Cost Daily Bar Chart

The following shows total dollars consumed.

Cost Pie chart

Solution cost

Let’s assume we’re calculating for an environment that runs 1,000 jobs daily, and we run this solution daily:

  • Lambda costs – One run requires 30 Lambda function invocations per month.
  • Amazon RDS cost – The total number of records in the public.emr_applications_execution_log table for a 30-day month would be 30,000 records, which translates to 5.72 MB of storage. If we consider the other two smaller tables and storage overhead, the overall monthly storage requirement would be approximately 12 MB.

In summary, the solution cost according to the AWS Pricing Calculator is $34.20/year, which is negligible.

Clean up

To avoid ongoing charges for the resources that you created, complete the following steps:

  • Delete the AWS CDK stacks:
    cdk destroy –-all

  • Delete the QuickSight report and dashboard, if created.
  • Run the following SQL to drop the tables:
    drop table public.emr_applications_execution_log_lz;
    drop table public.emr_applications_execution_log;
    drop table public.emr_cluster_usage_cost;
    drop table public.emr_cluster_instances_usage;

Conclusion

With this solution, you can deploy a chargeback model to attribute costs to users and groups using the EMR cluster. You can also identify options for optimization, scaling, and separation of workloads to different clusters based on usage and growth needs.

You can collect the metrics for a longer duration to observe trends on the usage of Amazon EMR resources and use that for forecasting purposes.

If you have any thoughts or questions, leave them in the comments section.


About the Authors

Raj Patel is AWS Lead Consultant for Data Analytics solutions based out of India. He specializes in building and modernising analytical solutions. His background is in data warehouse/data lake – architecture, development and administration. He is in data and analytical field for over 14 years.

Ramesh DPRamesh Raghupathy is a Senior Data Architect with WWCO ProServe at AWS. He works with AWS customers to architect, deploy, and migrate to data warehouses and data lakes on the AWS Cloud. While not at work, Ramesh enjoys traveling, spending time with family, and yoga.

Gaurav JainGaurav Jain is a Sr Data Architect with AWS Professional Services, specialized in big data and helps customers modernize their data platforms on the cloud. He is passionate about building the right analytics solutions to gain timely insights and make critical business decisions. Outside of work, he loves to spend time with his family and likes watching movies and sports.

Dipal Mahajan is a Lead Consultant with Amazon Web Services based out of India, where he guides global customers to build highly secure, scalable, reliable, and cost-efficient applications on the cloud. He brings extensive experience on Software Development, Architecture and Analytics from industries like finance, telecom, retail and healthcare.

Amazon EMR 7.1 runtime for Apache Spark and Iceberg can run Spark workloads 2.7 times faster than Apache Spark 3.5.1 and Iceberg 1.5.2

Post Syndicated from Hari Kishore Chaparala original https://aws.amazon.com/blogs/big-data/amazon-emr-7-1-runtime-for-apache-spark-and-iceberg-can-run-spark-workloads-2-7-times-faster-than-apache-spark-3-5-1-and-iceberg-1-5-2/

In this post, we explore the performance benefits of using the Amazon EMR runtime for Apache Spark and Apache Iceberg compared to running the same workloads with open source Spark 3.5.1 on Iceberg tables. Iceberg is a popular open source high-performance format for large analytic tables. Our benchmarks demonstrate that Amazon EMR can run TPC-DS 3 TB workloads 2.7 times faster, reducing the runtime from 1.548 hours to 0.564 hours. Additionally, the cost efficiency improves by 2.2 times, with the total cost decreasing from $16.09 to $7.23 when using Amazon Elastic Compute Cloud (Amazon EC2) On-Demand r5d.4xlarge instances, providing observable gains for data processing tasks.

The Amazon EMR runtime for Apache Spark offers a high-performance runtime environment while maintaining 100% API compatibility with open source Spark and Iceberg table format. In Run Apache Spark 3.5.1 workloads 4.5 times faster with Amazon EMR runtime for Apache Spark, we detailed some of the optimizations, showing a runtime improvement of 4.5 times faster and 2.8 times better price-performance compared to open source Spark 3.5.1 on the TPC-DS 3 TB benchmark. However, many of the optimizations are geared towards DataSource V1, whereas Iceberg uses Spark DataSource V2. Recognizing this, we have focused on migrating some of the existing optimizations in the EMR runtime for Spark to DataSource V2 and introducing Iceberg-specific enhancements. These improvements are built on top of the Spark runtime enhancements on query planning, physical plan operator improvements, and optimizations with Amazon Simple Storage Service (Amazon S3) and the Java runtime. We have added eight new optimizations incrementally since the Amazon EMR 6.15 release in 2023, which are present in Amazon EMR 7.1 and turned on by default. Some of the improvements include the following:

  • Optimizing DataSource V2 in Spark:
    • Dynamic filtering on non-partitioned columns
    • Removing redundant broadcast hash joins
    • Partial hash aggregate pushdowns
    • Bloom filter-based joins
  • Iceberg-specific enhancements:
    • Data prefetch
    • Support for file size-based estimations

Amazon EMR on EC2, Amazon EMR Serverless, Amazon EMR on Amazon EKS, and Amazon EMR on AWS Outposts all use the optimized runtimes. Refer to Working with Apache Iceberg in Amazon EMR and Best practices for optimizing Apache Iceberg workloads for more details.

Benchmark results for Amazon EMR 7.1 vs. open source Spark 3.5.1 and Iceberg 1.5.2

To assess the Spark engine’s performance with the Iceberg table format, we performed benchmark tests using the 3 TB TPC-DS dataset, version 2.13 (our results derived from the TPC-DS dataset are not directly comparable to the official TPC-DS results due to setup differences). Benchmark tests for the EMR runtime for Spark and Iceberg were conducted on Amazon EMR 7.1 clusters with Spark 3.5.0 and Iceberg 1.4.3-amzn-0 versions, and open source Spark 3.5.1 and Iceberg 1.5.2 was deployed on EC2 clusters designated for open source runs.

The setup instructions and technical details are available in our GitHub repository. To minimize the influence of external catalogs like AWS Glue and Hive, we used the Hadoop catalog for the Iceberg tables. This uses the underlying file system, specifically Amazon S3, as the catalog. We can define this setup by configuring the property spark.sql.catalog.<catalog_name>.type. The fact tables used the default partitioning by the date column, which have a number of partitions varying from 200–2,100. No precalculated statistics were used for these tables.

We ran a total of 104 SparkSQL queries in three sequential rounds, and the average runtime of each query across these rounds was taken for comparison. The average runtime for the three rounds on Amazon EMR 7.1 with Iceberg enabled was 0.56 hours, demonstrating a 2.7-fold speed increase compared to open source Spark 3.5.1 and Iceberg 1.5.2. The following figure presents the total runtimes in seconds.

The following table summarizes the metrics.

Metric Amazon EMR 7.1 on EC2 Open Source Spark 3.5.1 and Iceberg 1.5.2
Average runtime in seconds 2033.17 5575.19
Geometric mean over queries in seconds 10.13153 20.34651
Cost* $7.23 $16.09

*Detailed cost estimates are discussed later in this post.

The following chart demonstrates the per-query performance improvement of Amazon EMR 7.1 relative to open source Spark 3.5.1 and Iceberg 1.5.2. The extent of the speedup varies from one query to another, ranging from 9.6 times faster for q93 to 1.04 times faster for q34, with Amazon EMR outperforming the open source Spark with Iceberg tables. The horizontal axis arranges the TPC-DS 3 TB benchmark queries in descending order based on the performance improvement seen with Amazon EMR, and the vertical axis depicts the magnitude of this speedup in seconds.

Cost comparison

Our benchmark provides the total runtime and geometric mean data to assess the performance of Spark and Iceberg in a complex, real-world decision support scenario. For additional insights, we also examine the cost aspect. We calculate cost estimates using formulas that account for EC2 On-Demand instances, Amazon Elastic Block Store (Amazon EBS), and Amazon EMR expenses.

  • Amazon EC2 cost (includes SSD cost) = number of instances * r5d.4xlarge hourly rate * job runtime in hours
    • 4xlarge hourly rate = $1.152 per hour
  • Root Amazon EBS cost = number of instances * Amazon EBS per GB-hourly rate * root EBS volume size * job runtime in hours
  • Amazon EMR cost = number of instances * r5d.4xlarge Amazon EMR cost * job runtime in hours
    • 4xlarge Amazon EMR cost = $0.27 per hour
  • Total cost = Amazon EC2 cost + root Amazon EBS cost + Amazon EMR cost

The calculations reveal that the Amazon EMR 7.1 benchmark yields a 2.2-fold cost efficiency improvement over open source Spark 3.5.1 and Iceberg 1.5.2 in running the benchmark job.

Metric Amazon EMR 7.1 Open Source Spark 3.5.1 and Iceberg 1.5.2
Runtime in hours 0.564 1.548
Number of EC2 instances 9 9
Amazon EBS Size 20gb 20gb
Amazon EC2 cost $5.85 $16.05
Amazon EBS cost $0.01 $0.04
Amazon EMR cost $1.37 $0
Total cost $7.23 $16.09
Cost savings Amazon EMR 7.1 is 2.2 times better Baseline

In addition to the time-based metrics discussed so far, data from Spark event logs shows that Amazon EMR 7.1 scanned approximately 3.4 times less data from Amazon S3 and 4.1 times fewer records than the open source version in the TPC-DS 3 TB benchmark. This reduction in Amazon S3 data scanning contributes directly to cost savings for Amazon EMR workloads.

Run open source Spark benchmarks on Iceberg tables

We used separate EC2 clusters, each equipped with nine r5d.4xlarge instances, for testing both open source Spark 3.5.1 and Iceberg 1.5.2 and Amazon EMR 7.1. The primary node was equipped with 16 vCPU and 128 GB of memory, and the eight worker nodes together had 128 vCPU and 1024 GB of memory. We conducted tests using the Amazon EMR default settings to showcase the typical user experience and minimally adjusted the settings of Spark and Iceberg to maintain a balanced comparison.

The following table summarizes the Amazon EC2 configurations for the primary node and eight worker nodes of type r5d.4xlarge.

EC2 Instance vCPU Memory (GiB) Instance Storage (GB) EBS Root Volume (GB)
r5d.4xlarge 16 128 2 x 300 NVMe SSD 20 GB

Prerequisites

The following prerequisites are required to run the benchmarking:

  1. Using the instructions in the emr-spark-benchmark GitHub repo, set up the TPC-DS source data in your S3 bucket and on your local computer.
  2. Build the benchmark application following the steps provided in Steps to build spark-benchmark-assembly application and copy the benchmark application to your S3 bucket. Alternatively, copy spark-benchmark-assembly-3.5.1.jar to your S3 bucket.
  3. Create Iceberg tables from the TPC-DS source data. Follow the instructions on GitHub to create Iceberg tables using the Hadoop catalog. For example, the following code uses an EMR 7.1 cluster with Iceberg enabled to create the tables:
aws emr add-steps --cluster-id <cluster-id> --steps Type=Spark,Name="Create Iceberg Tables",
Args=[--class,com.amazonaws.eks.tpcds.CreateIcebergTables,
--conf,spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions,
--conf,spark.sql.catalog.hadoop_catalog=org.apache.iceberg.spark.SparkCatalog,
--conf,spark.sql.catalog.hadoop_catalog.type=hadoop,
--conf,spark.sql.catalog.hadoop_catalog.warehouse=s3://<bucket>/<warehouse_path>/,
--conf,spark.sql.catalog.hadoop_catalog.io-impl=org.apache.iceberg.aws.s3.S3FileIO,
s3://<bucket>/<jar_location>/spark-benchmark-assembly-3.5.1.jar,
s3://blogpost-sparkoneks-us-east-1/blog/BLOG_TPCDS-TEST-3T-partitioned/,
/home/hadoop/tpcds-kit/tools,parquet,3000,true,<database_name>,true,true],ActionOnFailure=CONTINUE 
--region <AWS region>

Note the Hadoop catalog warehouse location and database name from the preceding step. We use the same tables to run benchmarks with Amazon EMR 7.1 and open source Spark and Iceberg.

This benchmark application is built from the branch tpcds-v2.13_iceberg. If you’re building a new benchmark application, switch to the correct branch after downloading the source code from the GitHub repo.

Create and configure a YARN cluster on Amazon EC2

To compare Iceberg performance between Amazon EMR on Amazon EC2 and open source Spark on Amazon EC2, follow the instructions in the emr-spark-benchmark GitHub repo to create an open source Spark cluster on Amazon EC2 using Flintrock with eight worker nodes.

Based on the cluster selection for this test, the following configurations are used:

Run the TPC-DS benchmark with Apache Spark 3.5.1 and Iceberg 1.5.2

Complete the following steps to run the TPC-DS benchmark:

  1. Log in to the open source cluster primary using flintrock login $CLUSTER_NAME.
  2. Submit your Spark job:
    1. Choose the correct Iceberg catalog warehouse location and database that has the created Iceberg tables.
    2. The results are created in s3://<YOUR_S3_BUCKET>/benchmark_run.
    3. You can track progress in /media/ephemeral0/spark_run.log.
spark-submit \
--master yarn \
--deploy-mode client \
--class com.amazonaws.eks.tpcds.BenchmarkSQL \
--conf spark.driver.cores=4 \
--conf spark.driver.memory=10g \
--conf spark.executor.cores=16 \
--conf spark.executor.memory=100g \
--conf spark.executor.instances=8 \
--conf spark.network.timeout=2000 \
--conf spark.executor.heartbeatInterval=300s \
--conf spark.dynamicAllocation.enabled=false \
--conf spark.shuffle.service.enabled=false \
--conf spark.hadoop.fs.s3a.aws.credentials.provider=com.amazonaws.auth.InstanceProfileCredentialsProvider \
--conf spark.hadoop.fs.s3.impl=org.apache.hadoop.fs.s3a.S3AFileSystem \
--conf spark.jars.packages=org.apache.hadoop:hadoop-aws:3.3.4,org.apache.iceberg:iceberg-spark-runtime-3.5_2.12:1.5.2,org.apache.iceberg:iceberg-aws-bundle:1.5.2 \
--conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions   \
--conf spark.sql.catalog.local=org.apache.iceberg.spark.SparkCatalog    \
--conf spark.sql.catalog.local.type=hadoop  \
--conf spark.sql.catalog.local.warehouse=s3a://<YOUR_S3_BUCKET>/<warehouse_path>/ \
--conf spark.sql.defaultCatalog=local   \
--conf spark.sql.catalog.local.io-impl=org.apache.iceberg.aws.s3.S3FileIO   \
spark-benchmark-assembly-3.5.1.jar   \
s3://<YOUR_S3_BUCKET>/benchmark_run 3000 1 false  \
q1-v2.13,q10-v2.13,q11-v2.13,q12-v2.13,q13-v2.13,q14a-v2.13,q14b-v2.13,q15-v2.13,q16-v2.13,\
q17-v2.13,q18-v2.13,q19-v2.13,q2-v2.13,q20-v2.13,q21-v2.13,q22-v2.13,q23a-v2.13,q23b-v2.13,\
q24a-v2.13,q24b-v2.13,q25-v2.13,q26-v2.13,q27-v2.13,q28-v2.13,q29-v2.13,q3-v2.13,q30-v2.13,\
q31-v2.13,q32-v2.13,q33-v2.13,q34-v2.13,q35-v2.13,q36-v2.13,q37-v2.13,q38-v2.13,q39a-v2.13,\
q39b-v2.13,q4-v2.13,q40-v2.13,q41-v2.13,q42-v2.13,q43-v2.13,q44-v2.13,q45-v2.13,q46-v2.13,\
q47-v2.13,q48-v2.13,q49-v2.13,q5-v2.13,q50-v2.13,q51-v2.13,q52-v2.13,q53-v2.13,q54-v2.13,\
q55-v2.13,q56-v2.13,q57-v2.13,q58-v2.13,q59-v2.13,q6-v2.13,q60-v2.13,q61-v2.13,q62-v2.13,\
q63-v2.13,q64-v2.13,q65-v2.13,q66-v2.13,q67-v2.13,q68-v2.13,q69-v2.13,q7-v2.13,q70-v2.13,\
q71-v2.13,q72-v2.13,q73-v2.13,q74-v2.13,q75-v2.13,q76-v2.13,q77-v2.13,q78-v2.13,q79-v2.13,\
q8-v2.13,q80-v2.13,q81-v2.13,q82-v2.13,q83-v2.13,q84-v2.13,q85-v2.13,q86-v2.13,q87-v2.13,\
q88-v2.13,q89-v2.13,q9-v2.13,q90-v2.13,q91-v2.13,q92-v2.13,q93-v2.13,q94-v2.13,q95-v2.13,\
q96-v2.13,q97-v2.13,q98-v2.13,q99-v2.13,ss_max-v2.13    \
true <database> > /media/ephemeral0/spark_run.log 2>&1 &!

Summarize the results

After the Spark job finishes, retrieve the test result file from the output S3 bucket at s3://<YOUR_S3_BUCKET>/benchmark_run/timestamp=xxxx/summary.csv/xxx.csv. This can be done either through the Amazon S3 console by navigating to the specified bucket location or by using the Amazon Command Line Interface (AWS CLI). The Spark benchmark application organizes the data by creating a timestamp folder and placing a summary file within a folder labeled summary.csv. The output CSV files contain four columns without headers:

  • Query name
  • Median time
  • Minimum time
  • Maximum time

With the data from three separate test runs with one iteration each time, we can calculate the average and geometric mean of the benchmark runtimes.

Run the TPC-DS benchmark with the EMR runtime for Spark

Most of the instructions are similar to Steps to run Spark Benchmarking with a few Iceberg-specific details.

Prerequisites

Complete the following prerequisite steps:

  1. Run aws configure to configure the AWS CLI shell to point to the benchmarking AWS account. Refer to Configure the AWS CLI for instructions.
  2. Upload the benchmark application JAR file to Amazon S3.

Deploy the EMR cluster and run the benchmark job

Complete the following steps to run the benchmark job:

  1. Use the AWS CLI command as shown in Deploy EMR on EC2 Cluster and run benchmark job to spin up an EMR on EC2 cluster. Make sure to enable Iceberg. See Create an Iceberg cluster for more details. Choose the correct Amazon EMR version, root volume size, and same resource configuration as the open source Flintrock setup. Refer to create-cluster for a detailed description of the AWS CLI options.
  2. Store the cluster ID from the response. We need this for the next step.
  3. Submit the benchmark job in Amazon EMR using add-steps from the AWS CLI:
    1. Replace <cluster ID> with the cluster ID from Step 2.
    2. The benchmark application is at s3://<your-bucket>/spark-benchmark-assembly-3.5.1.jar.
    3. Choose the correct Iceberg catalog warehouse location and database that has the created Iceberg tables. This should be the same as the one used for the open source TPC-DS benchmark run.
    4. The results will be in s3://<your-bucket>/benchmark_run.
aws emr add-steps   --cluster-id <cluster-id>
--steps Type=Spark,Name="SPARK Iceberg EMR TPCDS Benchmark Job",
Args=[--class,com.amazonaws.eks.tpcds.BenchmarkSQL,
--conf,spark.driver.cores=4,
--conf,spark.driver.memory=10g,
--conf,spark.executor.cores=16,
--conf,spark.executor.memory=100g,
--conf,spark.executor.instances=8,
--conf,spark.network.timeout=2000,
--conf,spark.executor.heartbeatInterval=300s,
--conf,spark.dynamicAllocation.enabled=false,
--conf,spark.shuffle.service.enabled=false,
--conf,spark.sql.iceberg.data-prefetch.enabled=true,
--conf,spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions,
--conf,spark.sql.catalog.local=org.apache.iceberg.spark.SparkCatalog,
--conf,spark.sql.catalog.local.type=hadoop,
--conf,spark.sql.catalog.local.warehouse=s3://<your-bucket>/<warehouse-path>,
--conf,spark.sql.defaultCatalog=local,
--conf,spark.sql.catalog.local.io-impl=org.apache.iceberg.aws.s3.S3FileIO,
s3://<your-bucket>/spark-benchmark-assembly-3.5.1.jar,
s3://<your-bucket>/benchmark_run,3000,1,false,
'q1-v2.13\,q10-v2.13\,q11-v2.13\,q12-v2.13\,q13-v2.13\,q14a-v2.13\,
q14b-v2.13\,q15-v2.13\,q16-v2.13\,q17-v2.13\,q18-v2.13\,q19-v2.13\,
q2-v2.13\,q20-v2.13\,q21-v2.13\,q22-v2.13\,q23a-v2.13\,q23b-v2.13\,
q24a-v2.13\,q24b-v2.13\,q25-v2.13\,q26-v2.13\,q27-v2.13\,q28-v2.13\,
q29-v2.13\,q3-v2.13\,q30-v2.13\,q31-v2.13\,q32-v2.13\,q33-v2.13\,
q34-v2.13\,q35-v2.13\,q36-v2.13\,q37-v2.13\,q38-v2.13\,q39a-v2.13\,
q39b-v2.13\,q4-v2.13\,q40-v2.13\,q41-v2.13\,q42-v2.13\,q43-v2.13\,
q44-v2.13\,q45-v2.13\,q46-v2.13\,q47-v2.13\,q48-v2.13\,q49-v2.13\,
q5-v2.13\,q50-v2.13\,q51-v2.13\,q52-v2.13\,q53-v2.13\,q54-v2.13\,
q55-v2.13\,q56-v2.13\,q57-v2.13\,q58-v2.13\,q59-v2.13\,q6-v2.13\,
q60-v2.13\,q61-v2.13\,q62-v2.13\,q63-v2.13\,q64-v2.13\,q65-v2.13\,
q66-v2.13\,q67-v2.13\,q68-v2.13\,q69-v2.13\,q7-v2.13\,q70-v2.13\,
q71-v2.13\,q72-v2.13\,q73-v2.13\,q74-v2.13\,q75-v2.13\,q76-v2.13\,
q77-v2.13\,q78-v2.13\,q79-v2.13\,q8-v2.13\,q80-v2.13\,q81-v2.13\,
q82-v2.13\,q83-v2.13\,q84-v2.13\,q85-v2.13\,q86-v2.13\,q87-v2.13\,
q88-v2.13\,q89-v2.13\,q9-v2.13\,q90-v2.13\,q91-v2.13\,q92-v2.13\,
q93-v2.13\,q94-v2.13\,q95-v2.13\,q96-v2.13\,q97-v2.13\,q98-v2.13\,
q99-v2.13\,ss_max-v2.13',true,<database>],ActionOnFailure=CONTINUE 
--region <aws-region>

Summarize the results

After the step is complete, you can see the summarized benchmark result at s3://<YOUR_S3_BUCKET>/benchmark_run/timestamp=xxxx/summary.csv/xxx.csv in the same way as the previous run and compute the average and geometric mean of the query runtimes.

Clean up

To prevent any future charges, delete the resources you created by following the instructions provided in the Cleanup section of the GitHub repository.

Summary

Amazon EMR is consistently enhancing the EMR runtime for Spark when used with Iceberg tables, achieving a performance that is 2.7 times faster than open source Spark 3.5.1 and Iceberg 1.5.2 on TPC-DS 3 TB, v2.13. We encourage you to keep up to date with the latest Amazon EMR releases to fully benefit from ongoing performance improvements.

To stay informed, subscribe to the AWS Big Data Blog’s RSS feed, where you can find updates on the EMR runtime for Spark and Iceberg, as well as tips on configuration best practices and tuning recommendations.


About the authors

Hari Kishore Chaparala is a software development engineer for Amazon EMR at Amazon Web Services.

Udit Mehrotra is an Engineering Manager for EMR at Amazon Web Services.

Migrate data from an on-premises Hadoop environment to Amazon S3 using S3DistCp with AWS Direct Connect

Post Syndicated from Vicky Jacob original https://aws.amazon.com/blogs/big-data/migrate-data-from-an-on-premises-hadoop-environment-to-amazon-s3-using-s3distcp-with-aws-direct-connect/

This post demonstrates how to migrate nearly any amount of data from an on-premises Apache Hadoop environment to Amazon Simple Storage Service (Amazon S3) by using S3DistCp on Amazon EMR with AWS Direct Connect.

To transfer resources from a target EMR cluster, the traditional Hadoop DistCp must be run on the source cluster to move data from one cluster to another, which invokes a MapReduce job on the source cluster and can consume a lot of cluster resources (depending on the data volume). To avoid this problem and minimize the load on the source cluster, you can use S3DistCp with Direct Connect to migrate terabytes of data from an on-premises Hadoop environment to Amazon S3. This process runs the job on the target EMR cluster, minimizing the burden on the source cluster.

This post provides instructions for using S3DistCp for migrating data to the AWS Cloud. Apache DistCp is an open source tool that you can use to copy large amounts of data. S3DistCp is similar to DistCp, but optimized to work with AWS, particularly Amazon S3. When compared to Hadoop DistCp, S3DistCp is more scalable, with higher throughput and efficient for parallel copying of large numbers of objects across s3 buckets and across AWS accounts.

Solution overview

The architecture for this solution includes the following components:

  • Source technology stack:
    • A Hadoop cluster with connectivity to the target EMR cluster over Direct Connect
  • Target technology stack:

The following architecture diagram shows how you can use the S3DistCp from the target EMR cluster to migrate huge volumes of data from an on-premises Hadoop environment through a private network connection, such as Direct Connect to Amazon S3.

S3DistCpThis migration approach uses the following tools to perform the migration:

  • S3DistCp – S3DistCp is similar to DistCp, but optimized to work with AWS, particularly Amazon S3. The command for S3DistCp in Amazon EMR version 4.0 and later is s3-dist-cp, which you add as a step in a cluster or at the command line. With S3DistCp, you can efficiently copy large amounts of data from Amazon S3 into Hadoop Distributed Filed System (HDFS), where it can be processed by subsequent steps in your EMR cluster. You can also use S3DistCp to copy data between S3 buckets or from HDFS to Amazon S3. S3DistCp is more scalable and efficient for parallel copying of large numbers of objects across buckets and across AWS accounts.
  • Amazon S3 – Amazon S3 is an object storage service. You can use Amazon S3 to store and retrieve any amount of data at any time, from anywhere on the web.
  • Amazon VPC – Amazon VPC provisions a logically isolated section of the AWS Cloud where you can launch AWS resources in a virtual network that you’ve defined. This virtual network closely resembles a traditional network that you would operate in your own data center, with the benefits of using the scalable infrastructure of AWS.
  • AWS Identity and Access Management (IAM) – IAM is a web service for securely controlling access to AWS services. With IAM, you can centrally manage users, security credentials such as access keys, and permissions that control which AWS resources users and applications can access.
  • Direct Connect – Direct Connect links your internal network to a Direct Connect location over a standard ethernet fiber-optic cable. One end of the cable is connected to your router, the other to a Direct Connect router. With this connection, you can create virtual interfaces directly to public AWS services (for example, to Amazon S3) or to Amazon VPC, bypassing internet service providers in your network path. A Direct Connect location provides access to AWS in the AWS Region with which it’s associated. You can use a single connection in a public Region or in AWS GovCloud (US) to access public AWS services in all other public Regions.

In the following sections, we discuss the steps to perform the data migration using S3DistCp.

Prerequisites

Before you begin, you should have the following prerequisites:

Get the active NameNode from the source Hadoop cluster

Sign in to any of the nodes on the source cluster and run the following commands on bash to get the active NameNode on the cluster.

In newer versions of Hadoop, run the following command to get the service status, which will list the active NameNode on the cluster:

[hadoop@hadoopcluster01 ~]$ hdfs haadmin -getAllServiceState
hadoopcluster01.test.amazon.local:8020                active
hadoopcluster02.test.amazon.local:8020                standby
hadoopcluster03.test.amazon.local:8020                standby

On older versions of Hadoop, run the following method on bash to get the active NameNode on the cluster:

[hadoop@hadoopcluster01 ~]$ getActiveNameNode(){
    nameservice=$(hdfs getconf -confKey dfs.nameservices);
    ns=$(hdfs getconf -confKey dfs.ha.namenodes.${nameservice});
    IFS=',' read -ra ADDR <<< "$ns"
    activeNode=''
    for n in "${ADDR[@]}"; do
        state=$(hdfs haadmin -getServiceState $n)
        if [ $state = "active" ]; then
            echo "$state ==>$n"
            activeNode=$n
        fi
    done
    activeNodeFQDN=$(hdfs getconf -confKey dfs.namenode.rpc-address.${nameservice}.${activeNode})
    echo $activeNodeFQDN;
}

[hadoop@hadoopcluster01 ~]$ getActiveNameNode
active ==>namenode863
hadoopcluster01.test.amazon.local:8020

Validate connectivity from the EMR cluster to the source Hadoop cluster

As mentioned in the prerequisites, you should have an EMR cluster and attach a custom IAM role for Amazon EMR. Run the following command to validate the connectivity from the target EMR cluster to the source Hadoop cluster:

[hadoop@emrcluster01 ~]$ telnet hadoopcluster01.test.amazon.local 8020
Trying 192.168.0.1...
Connected to hadoopcluster01.test.amazon.local.
Escape character is '^]'.
^]

Alternatively, you can run the following command:

[hadoop@emrcluster01 ~]$ curl -v telnet://hadoopcluster01.test.amazon.local:8020
*   Trying 192.168.0.1:8020...
* Connected to hadoopcluster01.test.amazon.local (192.168.0.1) port 8020 (#0)

Validate if the source HDFS path exists

Check if the source HDFS path is valid. If the following command returns 0, indicating that it’s valid, you can proceed to the next step:

[hadoop@emrcluster01 ~]$ hdfs dfs -test -d hdfs://hadoopcluster01.test.amazon.local/user/hive/warehouse/test.db/test_table01
[hadoop@emrcluster01 ~]$ echo $?
0

Transfer data using S3DistCp

To transfer the source HDFS folder to the target S3 bucket, use the following command:

s3-dist-cp --src hdfs://hadoopcluster01.test.amazon.local/user/hive/warehouse/test.db/test_table01 --dest s3://<BUCKET_NAME>/user/hive/warehouse/test.db/test_table01

To transfer large files in multipart chunks, use the following command to set the chuck size:

s3-dist-cp --src hdfs://hadoopcluster01.test.amazon.local/user/hive/warehouse/test.db/test_table01 --dest s3://<BUCKET_NAME>/user/hive/warehouse/test.db/test_table01 --multipartUploadChunkSize=1024

This will invoke a MapReduce job on the target EMR cluster. Depending on the volume of the data and the bandwidth speed, the job can take a few minutes up to a few hours to complete.

To get the list of running yarn applications on the cluster, run the following command:

yarn application -list

Validate the migrated data

After the preceding MapReduce job completes successfully, use the following steps to validate the data copied over:

source_size=$(hdfs dfs -du -s hdfs://hadoopcluster01.test.amazon.local/user/hive/warehouse/test.db/test_table01 | awk -F' ' '{print $1}')
target_size=$(aws s3 ls --summarize --recursive s3://<BUCKET_NAME>/user/hive/warehouse/test.db/test_table01 | grep "Total Size:" | awk -F' ' '{print $3}')

printf "Source HDFS folder Size in bytes: $source_size"
printf "Target S3 folder Size in bytes: $target_size" 

If the source and target size aren’t equal, perform the cleanup step in the next section and repeat the preceding S3DistCp step.

Clean up partially copied or errored out partitions and files

S3DistCp doesn’t clean up partially copied files and partitions if it fails while copying. Clean up partially copied or errored out partitions and files before you reinitiate the S3DistCp process. To clean up objects on Amazon S3, use the following AWS CLI command to perform the delete operation:

aws s3 rm s3://<BUCKET_NAME>/path/to/the/object –recursive

Best practices

To avoid copy errors when using S3DistCP to copy a single file (instead of a directory) from Amazon S3 to HDFS, use Amazon EMR 5.33.0 or later, or Amazon EMR 6.3.0 or later.

Limitations

The following are limitations of this approach:

  • If S3DistCp is unable to copy some or all of the specified files, the cluster step fails and returns a non-zero error code. If this occurs, S3DistCp doesn’t clean up partially copied files.
  • S3DistCp doesn’t support concatenation for Parquet files. Use PySpark instead. For more information, see Concatenating Parquet files in Amazon EMR.
  • VPC limitations apply to Direct Connect for Amazon S3. For more information, see AWS Direct Connect quotas.

Conclusion

In this post, we demonstrated the power of S3DistCp to migrate huge volumes of data from a source Hadoop cluster to a target S3 bucket or HDFS on an EMR cluster. With S3DistCp, you can migrate terabytes of data without affecting the compute resources on the source cluster as compared to Hadoop DistCp.

For more information about using S3DistCp, see the following resources:


About the Author

Vicky Wilson Jacob is a Senior Data Architect with AWS Professional Services Analytics Practice. Vicky specializes in Big Data, Data Engineering, Machine Learning, Data Science and Generative AI. He is passionate about technology and solving customer challenges. At AWS, he works with companies helping customers implement big data, machine learning, analytics, and generative AI solutions on cloud. Outside of work, he enjoys spending time with family, singing, and playing guitar.