Tag Archives: artificial intelligence

Let’s Architect! Modern data architectures

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-modern-data-architectures-2/

Data is the fuel for AI; modern data is even more important for generative AI and advanced data analytics, producing more accurate, relevant, and impactful results. Modern data comes in various forms: real-time, unstructured, or user-generated. Each form requires a different solution. AWS’s data journey began with Amazon Simple Storage Service (Amazon S3) in 2006, marking the start of cloud-based data storage at scale. Since then, AWS has expanded its data offerings to cover the entire data lifecycle, offering a comprehensive ecosystem of services designed to harness the full potential of modern data, from ingestion and storage to processing and analysis, supporting the entire lifecycle of AI-driven innovation.

In this blog post, we will cover some AWS use cases for modern data architectures, showing how AWS enables organizations to leverage the power of data and generative AI technologies.

Key considerations when choosing a database for your generative AI applications

This blog focuses on selecting the right database for generative AI applications and provide knowledge that can enhance your understanding, guide your decision making, and ultimately lead to more successful AI projects. Selecting the right database for generative AI applications is not just about storage; it significantly impacts performance, scalability, ease of integration, and overall effectiveness of the AI solution.

Diagram that shows the key steps in a RAG workflow

Figure 1. Diagram that shows the key steps in a RAG workflow

Take me to this blog

Strategies for building a data mesh-based enterprise solution on AWS

Adopting a data mesh architecture can enhance an organization’s ability to manage data effectively, leading to improved performance, innovation, and overall business success. In this guidance, you will discover some strategies to build data mesh solutions on AWS.

Screenshot showing the AWS Prescriptive Guidance data mesh strategies page

Figure 2. The data mesh organizes data into domains, where data are seen as quality products to expose for consumption

Take me to this guidance

Optimizing storage price and performance with Amazon S3

Amazon S3 is an object storage service that supports multiple use cases, including data architectures. Big data pipelines can use Amazon S3 to store input, output, and intermediate results. Machine learning systems use Amazon S3 to process application logs and build the datasets both for experimentation and for production model training. Given the importance of the service and the number of use cases that a foundational storage service can support, we want to share best practices, performance optimization, and cost optimization strategies to work with Amazon S3. This video shows how Anthropic designs its architecture around Amazon S3 in their data architecture.

Storage class comparison chart showing classes of Amazon S3 options

Figure 3. Workloads with predictable patterns often have low retrieval rates for long periods of time after, so we can design to adopt cheaper storage classes for them

Take me to this video

If you are curious about the underlying architecture of Amazon S3 and want to drill down into its internal design, you can watch the re:Invent video Dive deep on Amazon S3.

How HPE Aruba Supply Chain optimized cost and performance by migrating to an AWS modern data architecture

This is an AWS case study on how HPE Aruba Supply Chain successfully re-architected and deployed their data solution by adopting a modern data architecture on AWS. The new solution has helped Aruba integrate data from multiple sources, along with optimizing their cost, performance, and scalability. This has also allowed the Aruba Supply Chain leadership to receive in-depth and timely insights for better decision-making, thereby elevating the customer experience.

Reference architecture diagram showing HPE Aruba Supply Chain's architecture, featuring Amazon S3

Figure 4. Reference architecture diagram showing HPE Aruba Supply Chain’s architecture, featuring Amazon S3

Take me to this blog

AWS Modern Data Architecture Immersion Day

This workshop highlights advantage of adopting a modern data architecture on AWS. By integrating the flexibility of a data lake with specialized analytics services, organizations can significantly enhance their data-driven decision-making capabilities. We encourage everyone to explore how this architecture can streamline their analytics processes and support diverse use cases, from real-time insights to advanced machine learning. It’s an excellent opportunity to leverage modern data architecture.

Diagram showing AWS services in a flywheel

Figure 5. Data architectures are fundamental to power use cases ranging from analytics to machine learning

Take me to this workshop

See you next time!

Thanks for reading! In the next blog, we will cover some tips on how to get the best out of your developer experience on AWS. To revisit any of our previous posts or explore the entire series, visit the Let’s Architect! page.

AIs Discovering Vulnerabilities

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/11/ais-discovering-vulnerabilities.html

I’ve been writing about the possibility of AIs automatically discovering code vulnerabilities since at least 2018. This is an ongoing area of research: AIs doing source code scanning, AIs finding zero-days in the wild, and everything in between. The AIs aren’t very good at it yet, but they’re getting better.

Here’s some anecdotal data from this summer:

Since July 2024, ZeroPath is taking a novel approach combining deep program analysis with adversarial AI agents for validation. Our methodology has uncovered numerous critical vulnerabilities in production systems, including several that traditional Static Application Security Testing (SAST) tools were ill-equipped to find. This post provides a technical deep-dive into our research methodology and a living summary of the bugs found in popular open-source tools.

Expect lots of developments in this area over the next few years.

This is what I said in a recent interview:

Let’s stick with software. Imagine that we have an AI that finds software vulnerabilities. Yes, the attackers can use those AIs to break into systems. But the defenders can use the same AIs to find software vulnerabilities and then patch them. This capability, once it exists, will probably be built into the standard suite of software development tools. We can imagine a future where all the easily findable vulnerabilities (not all the vulnerabilities; there are lots of theoretical results about that) are removed in software before shipping.

When that day comes, all legacy code would be vulnerable. But all new code would be secure. And, eventually, those software vulnerabilities will be a thing of the past. In my head, some future programmer shakes their head and says, “Remember the early decades of this century when software was full of vulnerabilities? That’s before the AIs found them all. Wow, that was a crazy time.” We’re not there yet. We’re not even remotely there yet. But it’s a reasonable extrapolation.

EDITED TO ADD: And Google’s LLM just discovered an exploitable zero-day.

Fine-tuning for Anthropic’s Claude 3 Haiku model in Amazon Bedrock is now generally available

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/fine-tuning-for-anthropics-claude-3-haiku-model-in-amazon-bedrock-is-now-generally-available/

Today, we are announcing the general availability of fine-tuning for Anthropic’s Claude 3 Haiku model in Amazon Bedrock in the US West (Oregon) AWS Region. Amazon Bedrock is the only fully managed service that provides you with the ability to fine-tune Claude models. You can now fine-tune and customize the Claude 3 Haiku model with your own task-specific training dataset to boost model accuracy, quality, and consistency to further tailor generative AI for your business.

Fine-tuning is a technique where a pre-trained large language model (LLM) is customized for a specific task by updating the weights and tuning hyperparameters like learning rate and batch size for optimal results.

Anthropic’s Claude 3 Haiku model is the fastest and most compact model in the Claude 3 model family. Fine-tuning Claude 3 Haiku offers significant advantages for businesses:

  • Customization – You can customize models that excel in areas crucial to your business compared to more general models by encoding company and domain knowledge.
  • Specialized performance – You can generate higher quality results and create unique user experiences that reflect your company’s proprietary information, brand, products, and more.
  • Task-specific optimization – You can enhance performance for domain-specific actions such as classification, interactions with custom APIs, or industry-specific data interpretation.
  • Data security – You can fine-tune with peace of mind in your secure AWS environment. Amazon Bedrock makes a separate copy of the base foundation model that is accessible only by you and trains this private copy of the model.

You can now optimize performance for specific business use cases by providing domain-specific labeled data to fine-tune the Claude 3 Haiku model in Amazon Bedrock.

In early 2024, we started to engage customers with a team of experts from the AWS Generative AI Innovation Center to help fine-tune Anthropic’s Claude models with their proprietary data sources. I’m happy to share that you can now fine-tune Anthropic’s Claude 3 Haiku model in Amazon Bedrock directly in the Amazon Bedrock console.

Get started with fine-tuning for Anthropic’s Claude 3 Haiku model in Amazon Bedrock
I will demonstrate how to easily fine-tune the Claude 3 Haiku model in Amazon Bedrock. To learn more about the fine-tuning workflow in detail, visit the AWS Machine Learning Blog post, Fine-tune Anthropic’s Claude 3 Haiku in Amazon Bedrock to boost model accuracy and quality.

To create a simple fine-tuning job in the Amazon Bedrock console, go to the Foundation models section in the navigation pane and select Custom models. In the Models section, select the Customize model button and then select Create Fine-tuning job.

Next, choose the model that you want to customize with your own data, give your resulting model a name, and optionally add encryption keys and any tags to associate with the model in the Model details section. Enter a name for the job and optionally add any tags for the job in the Job configuration section.

You can select the Amazon S3 location of the training dataset file and, if applicable, the validation dataset file in the Input data section.

Each dataset can be created using a JSON Lines (JSONL) file with multiple JSON lines using the single-turn or multi-turn messaging format. Each JSON line is a sample containing a system and message, an array of message objects.

I prepared some of the latest information about Anthropic’s Claude 3.5 Sonnet model in Amazon Bedrock. To learn more, visit Prepare the datasets in the Amazon Bedrock documentation.

{"system": "You are an helpful assistant.","messages":[{"role": "user", "content": "What’s the latest models to support Amazon Bedrock"},{"role": "assistant", "content": "Amazon Bedrock is a fully managed service that support Anthropic’s Claude 3 Sonnet, Haiku, and Opus models and the latest Claud 3.5 Sonnet model."}]}
{"system": "You are an helpful assistant.","messages":[{"role": "user", "content": "How long context window of Claude 3.5?"},{"role": "assistant", "content": "Anthropic's Claude 3 models have a 200,000 token context window enabling you to relay a large volume of information to Claude. This translates to roughly 150,000 words, or over 500 pages of material."}]}
{"system": "You are an helpful assistant.","messages":[{"role": "user", "content": "Is Claude 3.5 available in Bedrock?"},{"role": "assistant", "content": "Anthropic’s most intelligent and advanced model, Claude 3.5 Sonnet, demonstrates exceptional capabilities across a diverse range of tasks and evaluations while also outperforming Claude 3 Opus."}]}

In the Hyperparameters section, enter values for hyperparameters to use in training, such as epochs, batch size, and learning rate multiplier. If you’ve included a validation dataset, you can enable Early stopping, a technique used to prevent overfitting and stop the training process when the validation loss stops improving. You can set an early stopping threshold and patience value.

You can also select the output location where Amazon Bedrock should save the output of the job in the Output data section. Choose an AWS Identity and Access Management (IAM) custom service role with the appropriate permissions in the Service access section. To learn more, see Create a service role for model customization in the Amazon Bedrock documentation.

Finally, choose Create Fine-tuning job and wait for your fine-tuning job to start.

You can track its progress or stop it in the Jobs tab in the Custom models section.

After a model customization job is complete, you can analyze the results of the training process by looking at the files in the output Amazon Simple Storage Service (Amazon S3) folder that you specified when you submitted the job, or you can view details about the model.

Before using a customized model, you need to purchase Provisioned Throughput for Amazon Bedrock and then use the resulting provisioned model for inference. When you purchase Provisioned Throughput, you can select a commitment term, choose a number of model units, and see estimated hourly, daily, and monthly costs. To learn more about the custom model pricing for the Claude 3 Haiku model, visit Amazon Bedrock Pricing.

Now, you can test your custom model in the console playground. I choose my custom model and ask whether Anthropic’s Claude 3.5 Sonnet model is available in Amazon Bedrock.

I receive the answer:

Yes. You can use Anthropic’s most intelligent and advanced model, Claude 3.5 Sonnet in the Amazon Bedrock. You can demonstrate exceptional capabilities across a diverse range of tasks and evaluations while also outperforming Claude 3 Opus.

You can complete this job using AWS APIs, AWS SDKs, or AWS Command Line Interface (AWS CLI). To learn more about using AWS CLI, visit Code samples for model customization in the AWS documentation.

If you are using Jupyter Notebook, visit the GitHub repository and follow a hands-on guide for custom models. To build a production-level operation, I recommend reading Streamline custom model creation and deployment for Amazon Bedrock with Provisioned Throughput using Terraform on the AWS Machine Learning Blog.

Datasets and parameters
When fine-tuning Claude 3 Haiku, the first thing you should do is look at your datasets. There are two datasets that are involved in training Haiku, and that’s the Training dataset and the Validation dataset. There are specific parameters that you must follow in order to make your training successful, which are outlined in the following table.

Training data Validation data
File format JSONL
File size <= 10GB <= 1GB
Line count 32 – 10,000 lines 32 – 1,000 lines
Training + Validation Sum <= 10,000 lines
Token limit < 32,000 tokens per entry
Reserved keywords Avoid having “\nHuman:” or “\nAssistant:” in prompts

When you prepare the datasets, start with a small high-quality dataset and iterate based on tuning results. You can consider using larger models from Anthropic like Claude 3 Opus or Claude 3.5 Sonnet to help refine and improve your training data. You can also use them to generate training data for fine-tuning the Claude 3 Haiku model, which can be very effective if the larger models already perform well on your target task.

For more guidance on selecting the proper hyperparameters and preparing the datasets, read the AWS Machine Learning Blog post, Best practices and lessons for fine-tuning Anthropic’s Claude 3 Haiku in Amazon Bedrock.

Demo video
Check out this deep dive demo video for a step-by-step walkthrough that will help you get started with fine-tuning Anthropic’s Claude 3 Haiku model in Amazon Bedrock.

Now available
Fine-tuning for Anthropic’s Claude 3 Haiku model in Amazon Bedrock is now generally available in the US West (Oregon) AWS Region; check the full Region list for future updates. To learn more, visit Custom models in the Amazon Bedrock documentation.

Give fine-tuning for the Claude 3 Haiku model a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

I look forward to seeing what you build when you put this new technology to work for your business.

— Channy

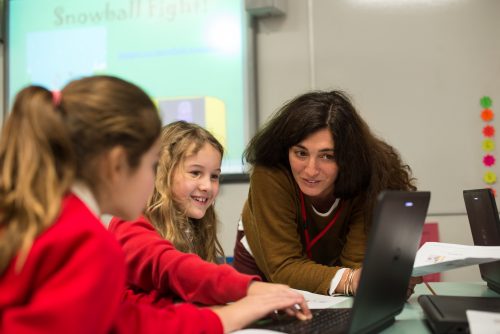
Teaching about AI in schools: Take part in our Research and Educator Community Symposium

Post Syndicated from Jane Waite original https://www.raspberrypi.org/blog/teaching-about-ai-in-schools-research-and-educator-community-symposium/

Worldwide, the use of generative AI systems and related technologies is transforming our lives. From marketing and social media to education and industry, these technologies are being used everywhere, even if it isn’t obvious. Yet, despite the growing availability and use of generative AI tools, governments are still working out how and when to regulate such technologies to ensure they don’t cause unforeseen negative consequences.

How, then, do we equip our young people to deal with the opportunities and challenges that they are faced with from generative AI applications and associated systems? Teaching them about AI technologies seems an important first step. But what should we teach, when, and how?

A teacher aids children in the classroom

Researching AI curriculum design

The researchers at the Raspberry Pi Foundation have been looking at research that will help inform curriculum design and resource development to teach about AI in school. As part of this work, a number of research themes have been established, which we would like to explore with educators at a face-to-face symposium. 

These research themes include the SEAME model, a simple way to analyse learning experiences about AI technology, as well as anthropomorphisation and how this might influence the formation of mental models about AI products. These research themes have become the cornerstone of the Experience AI resources we’ve co-developed with Google DeepMind. We will be using these materials to exemplify how the research themes can be used in practice as we review the recently published UNESCO AI competencies.

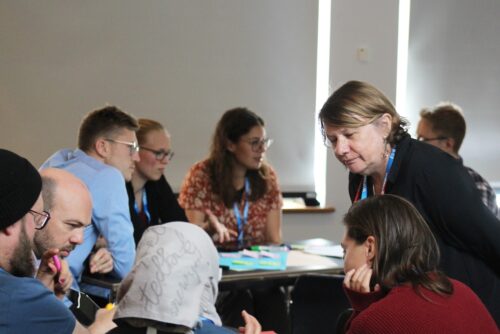
A group of educators at a workshop.

Most importantly, we will also review how we can help teachers and learners move from a rule-based view of problem solving to a data-driven view, from computational thinking 1.0 to computational thinking 2.0.

A call for teacher input on the AI curriculum

Over ten years ago, teachers in England experienced a large-scale change in what they needed to teach in computing lessons when programming was more formally added to the curriculum. As we enter a similar period of change — this time to introduce teaching about AI technologies — we want to hear from teachers as we collectively start to rethink our subject and curricula. 

We think it is imperative that educators’ voices are heard as we reimagine computer science and add data-driven technologies into an already densely packed learning context. 

Educators at a workshop.

Join our Research and Educator Community Symposium

On Saturday, 1 February 2025, we are running a Research and Educator Community Symposium in collaboration with the Raspberry Pi Computing Education Research Centre. 

In this symposium, we will bring together UK educators and researchers to review research themes, competency frameworks, and early international AI curricula and to reflect on how to advance approaches to teaching about AI. This will be a practical day of collaboration to produce suggested key concepts and pedagogical approaches and highlight research needs. 

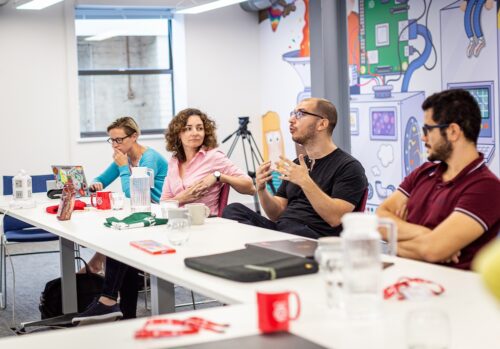
Educators and researchers at an event.

This symposium focuses on teaching about AI technologies, so we will not be looking at which AI tools might be used in general teaching and learning or how they may change teacher productivity. 

It is vitally important for young people to learn how to use AI technologies in their daily lives so they can become discerning consumers of AI applications. But how should we teach them? Please help us start to consider the best approach by signing up for our Research and Educator Community Symposium by 9 December 2024.

Information at a glance

When:  Saturday, 1 February 2025 (10am to 5pm) 

Where: Raspberry Pi Foundation Offices, Cambridge

Who: If you have started teaching about AI, are creating related resources, are providing professional development about AI technologies, or if you are planning to do so, please apply to attend our symposium. Travel funding is available for teachers in England.

Please note we expect to be oversubscribed, so book early and tell us about why you are interested in taking part. We will notify all applicants of the outcome of their application by 11 December.

The post Teaching about AI in schools: Take part in our Research and Educator Community Symposium appeared first on Raspberry Pi Foundation.

Introducing new artificial intelligence and machine learning projects for Code Clubs

Post Syndicated from Pete Bell original https://www.raspberrypi.org/blog/artificial-intelligence-projects-for-kids/

We’re pleased to share a new collection of Code Club projects designed to introduce creators to the fascinating world of artificial intelligence (AI) and machine learning (ML). These projects bring the latest technology to your Code Club in fun and inspiring ways, making AI and ML engaging and accessible for young people. We’d like to thank Amazon Future Engineer for supporting the development of this collection.

A man on a blue background, with question marks over his head, surrounded by various objects and animals, such as apples, planets, mice, a dinosaur and a shark.

The value of learning about AI and ML

By engaging with AI and ML at a young age, creators gain a clearer understanding of the capabilities and limitations of these technologies, helping them to challenge misconceptions. This early exposure also builds foundational skills that are increasingly important in various fields, preparing creators for future educational and career opportunities. Additionally, as AI and ML become more integrated into educational standards, having a strong base in these concepts will make it easier for creators to grasp more advanced topics later on.

What’s included in this collection

We’re excited to offer a range of AI and ML projects that feature both video tutorials and step-by-step written guides. The video tutorials are designed to guide creators through each activity at their own pace and are captioned to improve accessibility. The step-by-step written guides support creators who prefer learning through reading. 

The projects are crafted to be flexible and engaging. The main part of each project can be completed in just a few minutes, leaving lots of time for customisation and exploration. This setup allows for short, enjoyable sessions that can easily be incorporated into Code Club activities.

The collection is organised into two distinct paths, each offering a unique approach to learning about AI and ML:

Machine learning with Scratch introduces foundational concepts of ML through creative and interactive projects. Creators will train models to recognise patterns and make predictions, and explore how these models can be improved with additional data.

The AI Toolkit introduces various AI applications and technologies through hands-on projects using different platforms and tools. Creators will work with voice recognition, facial recognition, and other AI technologies, gaining a broad understanding of how AI can be applied in different contexts.

Inclusivity is a key aspect of this collection. The projects cater to various skill levels and are offered alongside an unplugged activity, ensuring that everyone can participate, regardless of available resources. Creators will also have the opportunity to stretch themselves — they can explore advanced technologies like Adobe Firefly and practical tools for managing Ollama and Stable Diffusion models on Raspberry Pi computers.

Project examples

A piece of cheese is displayed on a screen. There are multiple mice around the screen.

One of the highlights of our new collection is Chomp the cheese, which uses Scratch Lab’s experimental face recognition technology to create a game students can play with their mouth! This project offers a playful introduction to facial recognition while keeping the experience interactive and fun. 

A big orange fish on a dark blue background, with green leaves surrounding the fish.

Fish food uses Machine Learning for Kids, with creators training a model to control a fish using voice commands.

An illustration of a pink brain is displayed on a screen. There are two hands next to the screen playing the 'Rock paper scissors' game.

In Teach a machine, creators train a computer to recognise different objects such as fingers or food items. This project introduces classification in a straightforward way using the Teachable Machine platform, making the concept easy to grasp. 

Two men on a blue background, surrounded by question marks, a big green apple and a red tomato.

Apple vs tomato also uses Teachable Machine, but this time creators are challenged to train a model to differentiate between apples and tomatoes. Initially, the model exhibits bias due to limited data, prompting discussions on the importance of data diversity and ethical AI practices. 

Three people on a light blue background, surrounded by music notes and a microbit.

Dance detector allows creators to use accelerometer data from a micro:bit to train a model to recognise dance moves like Floss or Disco. This project combines physical computing with AI, helping creators explore movement recognition technology they may have experienced in familiar contexts such as video games. 

A green dinosaur in a forest is being observed by a person hiding in the bush holding the binoculars.

Dinosaur decision tree is an unplugged activity where creators use a paper-based branching chart to classify different types of dinosaurs. This hands-on project introduces the concept of decision-making structures, where each branch of the chart represents a choice or question leading to a different outcome. By constructing their own decision tree, creators gain a tactile understanding of how these models are used in ML to analyse data and make predictions. 

These AI projects are designed to support young people to get hands-on with AI technologies in Code Clubs and other non-formal learning environments. Creators can also enter one of their projects into Coolest Projects by taking a short video showing their project and any code used to make it. Their creation will then be showcased in the online gallery for people all over the world to see.

The post Introducing new artificial intelligence and machine learning projects for Code Clubs appeared first on Raspberry Pi Foundation.

Watermark for LLM-Generated Text

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/watermark-for-llm-generated-text.html

Researchers at Google have developed a watermark for LLM-generated text. The basics are pretty obvious: the LLM chooses between tokens partly based on a cryptographic key, and someone with knowledge of the key can detect those choices. What makes this hard is (1) how much text is required for the watermark to work, and (2) how robust the watermark is to post-generation editing. Google’s version looks pretty good: it’s detectable in text as small as 200 tokens.

Upgraded Claude 3.5 Sonnet from Anthropic (available now), computer use (public beta), and Claude 3.5 Haiku (coming soon) in Amazon Bedrock

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/upgraded-claude-3-5-sonnet-from-anthropic-available-now-computer-use-public-beta-and-claude-3-5-haiku-coming-soon-in-amazon-bedrock/

Four months ago, we introduced Anthropic’s Claude 3.5 in Amazon Bedrock, raising the industry bar for AI model intelligence while maintaining the speed and cost of Claude 3 Sonnet.

Today, I am excited to announce three new capabilities for the Claude 3.5 model family in Amazon Bedrock:

Upgraded Claude 3.5 Sonnet – You now have access to an upgraded Claude 3.5 Sonnet model that builds upon its predecessor’s strengths, offering even more intelligence at the same cost. Claude 3.5 Sonnet continues to improve its capability to solve real-world software engineering tasks and follow complex, agentic workflows. The upgraded Claude 3.5 Sonnet helps across the entire software development lifecycle, from initial design to bug fixes, maintenance, and optimizations. With these capabilities, the upgraded Claude 3.5 Sonnet model can help build more advanced chatbots with a warm, human-like tone. Other use cases in which the upgraded model excels include knowledge Q&A platforms, data extraction from visuals like charts and diagrams, and automation of repetitive tasks and operations.

Computer use – Claude 3.5 Sonnet now offers computer use capabilities in Amazon Bedrock in public beta, allowing Claude to perceive and interact with computer interfaces. Developers can direct Claude to use computers the way people do: by looking at a screen, moving a cursor, clicking buttons, and typing text. This works by giving the model access to integrated tools that can return computer actions, like keystrokes and mouse clicks, editing text files, and running shell commands. Software developers can integrate computer use in their solutions by building an action-execution layer and grant screen access to Claude 3.5 Sonnet. In this way, software developers can build applications with the ability to perform computer actions, follow multiple steps, and check their results. Computer use opens new possibilities for AI-powered applications. For example, it can help automate software testing and back office tasks and implement more advanced software assistants that can interact with applications. Given this technology is early, developers are encouraged to explore lower-risk tasks and use it in a sandbox environment.

Claude 3.5 Haiku – The new Claude 3.5 Haiku is coming soon and combines rapid response times with improved reasoning capabilities, making it ideal for tasks that require both speed and intelligence. Claude 3.5 Haiku improves on its predecessor and matches the performance of Claude 3 Opus (previously Claude’s largest model) at the speed and cost of Claude 3 Haiku. Claude 3.5 Haiku can help with use cases such as fast and accurate code suggestions, highly interactive chatbots that need rapid response times for customer service, e-commerce solutions, and educational platforms. For customers dealing with large volumes of unstructured data in finance, healthcare, research, and more, Claude 3.5 Haiku can help efficiently process and categorize information.

According to Anthropic, the upgraded Claude 3.5 Sonnet delivers across-the-board improvements over its predecessor, with significant gains in coding, an area where it already excelled. The upgraded Claude 3.5 Sonnet shows wide-ranging improvements on industry benchmarks. On coding, it improves performance on SWE-bench Verified from 33% to 49%, scoring higher than all publicly available models. It also improves performance on TAU-bench, an agentic tool use task, from 62.6% to 69.2% in the retail domain, and from 36.0% to 46.0% in the airline domain. The following table includes the model evaluations provided by Anthropic.

UPgraded Claude 3.5 Sonnet evaluations

Computer use, a new frontier in AI interaction
Instead of restricting the model to use APIs, Claude has been trained on general computer skills, allowing it to use a wide range of standard tools and software programs. In this way, applications can use Claude to perceive and interact with computer interfaces. Software developers can integrate this API to enable Claude to translate prompts (for example, “find me a hotel in Rome”) into specific computer commands (open a browser, navigate this website, and so on).

More specifically, when invoking the model, software developers now have access to three new integrated tools that provide a virtual set of hands to operate a computer:

  • Computer tool – This tool can receive as input a screenshot and a goal and returns a description of the mouse and keyboard actions that should be performed to achieve that goal. For example, this tool can ask to move the cursor to a specific position, click, type, and take screenshots.
  • Text editor tool – Using this tool, the model can ask to perform operations like viewing file contents, creating new files, replacing text, and undoing edits.
  • Bash tool – This tool returns commands that can be run on a computer system to interact at a lower level as a user typing in a terminal.

These tools open up a world of possibilities for automating complex tasks, from data analysis and software testing to content creation and system administration. Imagine an application powered by Claude 3.5 Sonnet interacting with the computer just as a human would, navigating through multiple desktop tools including terminals, text editors, internet browsers, and also capable of filling out forms and even debugging code.

We’re excited to help software developers explore these new capabilities with Amazon Bedrock. We expect this capability to improve rapidly in the coming months, and Claude’s current ability to use computers has limits. Some actions such as scrolling, dragging, or zooming can present challenges for Claude, and we encourage you to start exploring low-risk tasks.

When looking at OSWorld, a benchmark for multimodal agents in real computer environments, the upgraded Claude 3.5 Sonnet currently gets 14.9%. While human-level skill is far ahead with about 70-75%, this result is much better than the 7.7% obtained by the next-best model in the same category.

Using the upgraded Claude 3.5 Sonnet in the Amazon Bedrock console
To get started with the upgraded Claude 3.5 Sonnet, I navigate to the Amazon Bedrock console and choose Model access in the navigation pane. There, I request access for the new Claude 3.5 Sonnet V2 model.

To test the new vision capability, I open another browser tab and download from the Our World in Data website the Wind power generation chart in PNG format.

Our Word in Data – Wind power generation chart

Back in the Amazon Bedrock console, I choose Chat/text under Playgrounds in the navigation pane. For the model, I select Anthropic as the model provider and then Claude 3.5 Sonnet V2.

I use the three vertical dots in the input section of the chat to upload the image file from my computer. Then I enter this prompt:

Which are the top countries for wind power generation? Answer only in JSON.

The result follows my instructions and returns the list extracting the information from the image.

Console screenshot.

Using the upgraded Claude 3.5 Sonnet with AWS CLI and SDKs
Here’s a sample AWS Command Line Interface (AWS CLI) command using the Amazon Bedrock Converse API. I use the --query parameter of the CLI to filter the result and only show the text content of the output message:

aws bedrock-runtime converse \
    --model-id anthropic.claude-3-5-sonnet-20241022-v2:0 \
    --messages '[{ "role": "user", "content": [ { "text": "What do you throw out when you want to use it, but take in when you do not want to use it?" } ] }]' \
    --query 'output.message.content[*].text' \
    --output text

In output, I get this text in the response.

An anchor! You throw an anchor out when you want to use it to stop a boat, but you take it in (pull it up) when you don't want to use it and want to move the boat.

The AWS SDKs implement a similar interface. For example, you can use the AWS SDK for Python (Boto3) to analyze the same image as in the console example:

import boto3

MODEL_ID = "anthropic.claude-3-5-sonnet-20241022-v2:0"
IMAGE_NAME = "wind-generation.png"

bedrock_runtime = boto3.client("bedrock-runtime")

with open(IMAGE_NAME, "rb") as f:
    image = f.read()

user_message = "Which are the top countries for wind power generation? Answer only in JSON."

messages = [
    {
        "role": "user",
        "content": [
            {"image": {"format": "png", "source": {"bytes": image}}},
            {"text": user_message},
        ],
    }
]

response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=messages,
)
response_text = response["output"]["message"]["content"][0]["text"]
print(response_text)

Integrating computer use with your application
Let’s see how computer use works in practice. First, I take a snapshot of the desktop of a Ubuntu system:

Ubuntu desktop screenshot

This screenshot is the starting point for the steps that will be implemented by computer use. To see how that works, I run a Python script passing in input to the model the screenshot image and this prompt:

Find me a hotel in Rome.

This script invokes the upgraded Claude 3.5 Sonnet in Amazon Bedrock using the new syntax required for computer use:

import base64
import json
import boto3

MODEL_ID = "anthropic.claude-3-5-sonnet-20241022-v2:0"

IMAGE_NAME = "ubuntu-screenshot.png"

bedrock_runtime = boto3.client(
    "bedrock-runtime",
    region_name="us-east-1",
)

with open(IMAGE_NAME, "rb") as f:
    image = f.read()

image_base64 = base64.b64encode(image).decode("utf-8")

prompt = "Find me a hotel in Rome."

body = {
    "anthropic_version": "bedrock-2023-05-31",
    "max_tokens": 512,
    "temperature": 0.5,
    "messages": [
        {
            "role": "user",
            "content": [
                {"type": "text", "text": prompt},
                {
                    "type": "image",
                    "source": {
                        "type": "base64",
                        "media_type": "image/jpeg",
                        "data": image_base64,
                    },
                },
            ],
        }
    ],
    "tools": [
        { # new
            "type": "computer_20241022", # literal / constant
            "name": "computer", # literal / constant
            "display_height_px": 1280, # min=1, no max
            "display_width_px": 800, # min=1, no max
            "display_number": 0 # min=0, max=N, default=None
        },
        { # new
            "type": "bash_20241022", # literal / constant
            "name": "bash", # literal / constant
        },
        { # new
            "type": "text_editor_20241022", # literal / constant
            "name": "str_replace_editor", # literal / constant
        }
    ],
    "anthropic_beta": ["computer-use-2024-10-22"],
}

# Convert the native request to JSON.
request = json.dumps(body)

try:
    # Invoke the model with the request.
    response = bedrock_runtime.invoke_model(modelId=MODEL_ID, body=request)

except Exception as e:
    print(f"ERROR: {e}")
    exit(1)

# Decode the response body.
model_response = json.loads(response["body"].read())
print(model_response)

The body of the request includes new options:

  • anthropic_beta with value ["computer-use-2024-10-22"] to enable computer use.
  • The tools section supports a new type option (set to custom for the tools you configure).
  • Note that the computer tool needs to know the resolution of the screen (display_height_px and display_width_px).

To follow my instructions with computer use, the model provides actions that operate on the desktop described by the input screenshot.

The response from the model includes a tool_use section from the computer tool that provides the first step. The model has found in the screenshot the Firefox browser icon and the position of the mouse arrow. Because of that, it now asks to move the mouse to specific coordinates to start the browser.

{
    "id": "msg_bdrk_01WjPCKnd2LCvVeiV6wJ4mm3",
    "type": "message",
    "role": "assistant",
    "model": "claude-3-5-sonnet-20241022",
    "content": [
        {
            "type": "text",
            "text": "I'll help you search for a hotel in Rome. I see Firefox browser on the desktop, so I'll use that to access a travel website.",
        },
        {
            "type": "tool_use",
            "id": "toolu_bdrk_01CgfQ2bmQsPFMaqxXtYuyiJ",
            "name": "computer",
            "input": {"action": "mouse_move", "coordinate": [35, 65]},
        },
    ],
    "stop_reason": "tool_use",
    "stop_sequence": None,
    "usage": {"input_tokens": 3443, "output_tokens": 106},
}

This is just the first step. As with usual tool use requests, the script should reply with the result of using the tool (moving the mouse in this case). Based on the initial request to book a hotel, there would be a loop of tool use interactions that will ask to click on the icon, type a URL in the browser, and so on until the hotel has been booked.

A more complete example is available in this repository shared by Anthropic.

Things to know
The upgraded Claude 3.5 Sonnet is available today in Amazon Bedrock in the US West (Oregon) AWS Region and is offered at the same cost as the original Claude 3.5 Sonnet. For up-to-date information on regional availability, refer to the Amazon Bedrock documentation. For detailed cost information for each Claude model, visit the Amazon Bedrock pricing page.

In addition to the greater intelligence of the upgraded model, software developers can now integrate computer use (available in public beta) in their applications to automate complex desktop workflows, enhance software testing processes, and create more sophisticated AI-powered applications.

Claude 3.5 Haiku will be released in the coming weeks, initially as a text-only model and later with image input.

You can see how computer use can help with coding in this video with Alex Albert, Head of Developer Relations at Anthropic.

This other video describes computer use for automating operations.

To learn more about these new features, visit the Claude models section of the Amazon Bedrock documentation. Give the upgraded Claude 3.5 Sonnet a try in the Amazon Bedrock console today, and send feedback to AWS re:Post for Amazon Bedrock. You can find deep-dive technical content and discover how our Builder communities are using Amazon Bedrock at community.aws. Let us know what you build with these new capabilities!

– Danilo

AWS Weekly Roundup: Agentic workflows, Amazon Transcribe, AWS Lambda insights, and more (October 21, 2024)

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-agentic-workflows-amazon-transcribe-aws-lambda-insights-and-more-october-21-2024/

Agentic workflows are quickly becoming a cornerstone of AI innovation, enabling intelligent systems to autonomously handle and refine complex tasks in a way that mirrors human problem-solving. Last week, we launched Serverless Agentic Workflows with Amazon Bedrock, a new short course developed in collaboration with Dr. Andrew Ng and DeepLearning.AI.

Serverless Agentic Workflows with Amazon Bedrock

This hands-on course, taught by my colleague Mike Chambers, teaches how to build serverless agents that can handle complex tasks without the hassle of managing infrastructure. You will learn everything you need to know about integrating tools, automating workflows, and deploying responsible agents with built-in guardrails on Amazon Web Services (AWS) with Amazon Bedrock. The hands-on labs provided with the course let you apply your knowledge directly in an AWS environment, hosted by AWS Partner Vocareum. Find more information and enroll for free on the DeepLearning.AI course page.

Now, let’s turn our attention to other exciting news in the AWS universe from last week.

Last week’s launches
Here are some launches that got my attention:

Amazon Transcribe now supports streaming transcription in 30 additional languages – Amazon Transcribe has expanded its support to include 30 additional languages, bringing the total number of supported languages to 54. This enhancement helps you reach a broader global audience and improves accessibility across various industries, including contact centers, broadcasting, and e-learning. The expanded language support allows for more efficient content moderation, improved agent productivity, and automatic subtitling for live events and meetings.

AWS Lambda console now surfaces key function insights and supports real-time log analytics – The AWS Lambda console now features a built-in Amazon CloudWatch Metrics Insights dashboard and supports CloudWatch Logs Live Tail, providing instant visibility into critical function metrics and real-time log streaming. You can now identify and troubleshoot errors or performance issues for your Lambda functions without leaving the console, as well as view and analyze logs in real time as they become available. You can reduce context switching and accelerate the development and troubleshooting processes for serverless applications. Check out the launch post for more details.

Amazon Bedrock Model Evaluation now supports evaluating custom model import models – You can now evaluate custom models you’ve imported to Amazon Bedrock using the model evaluation feature. This helps you to complete the full cycle of selecting, customizing, and evaluating models before deploying them. To evaluate an imported model, select the custom model from the list of models to evaluate in the model selector tool when creating an evaluation job.

Amazon Q in AWS Supply Chain – You can now use Amazon Q, an interactive AI assistant, to analyze your supply chain data in AWS Supply Chain and get insights to operate your supply chain more efficiently. Amazon Q can answer your supply chain questions by diving into your data. This reduces the time spent searching for information and streamlines finding answers to improve your supply chain operations.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS news
Here are some additional news items and posts that you might find interesting:

New Amazon OpenSearch Service YouTube channel – The channel offers bite-sized tutorials, curated content, and organized playlists on topics such as log analytics, semantic search, vector databases, and operational best practices. You can also provide feedback to influence future channel content and the OpenSearch Service roadmap. Check out the launch post for more details and subscribe to the Amazon OpenSearch Service YouTube channel.

Deploying Generative AI Applications with NVIDIA NIM Microservices on Amazon Elastic Kubernetes Service (Amazon EKS) – This post shows you how to use Amazon EKS to orchestrate the deployment of pods containing NVIDIA NIM microservices, to enable quick-to-setup and optimized large-scale large language model (LLM) inference on Amazon EC2 G5 instances. It also demonstrates how to scale (both pod and cluster) by monitoring for custom metrics through Prometheus, and how you can load balance using an Application Load Balancer.

Instant Well-Architected CDK Resources with Solutions Constructs Factories – You can now create well-architected AWS resources such as Amazon Simple Storage Service (Amazon S3) buckets and AWS Step Functions state machines with a single function call using the new AWS Solutions Constructs Factories. These factories handle all the best practices configuration for you while still allowing customization. Try using a Constructs factory the next time you need to deploy one of the supported resources.

Upcoming AWS events
Check your calendars and sign up for these AWS events:

AWS GenAI LoftsAWS GenAI Lofts – AWS GenAI Lofts are about more than just the tech, they bring together startups, developers, investors, and industry experts. Whether you’re looking to gain deep insights, or get your questions answered by generative AI pros, our GenAI Lofts have you covered and provide everything you need to start building your next innovation. Join events in London (through October 25), Seoul (October 30–November 6), São Paulo (through November 20), and Paris (through November 25).

AWS Community DaysAWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Malta (November 8), Chile (November 9), and Kochi, India (December 14).

AWS re:Invent 2024AWS re:Invent – Registration is now open for the annual tech extravaganza, taking place December 2–6 in Las Vegas. At re:Invent 2024, you’ll get a front row seat to hear real stories from customers and AWS leaders about navigating pressing topics, such as generative AI. Learn about new product launches, watch demos, and get behind-the-scenes insights during five headline-making keynotes.

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Antje

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

AI and the SEC Whistleblower Program

Post Syndicated from B. Schneier original https://www.schneier.com/blog/archives/2024/10/ai-and-the-sec-whistleblower-program.html

Tax farming is the practice of licensing tax collection to private contractors. Used heavily in ancient Rome, it’s largely fallen out of practice because of the obvious conflict of interest between the state and the contractor. Because tax farmers are primarily interested in short-term revenue, they have no problem abusing taxpayers and making things worse for them in the long term. Today, the U.S. Securities and Exchange Commission (SEC) is engaged in a modern-day version of tax farming. And the potential for abuse will grow when the farmers start using artificial intelligence.

In 2009, after Bernie Madoff’s $65 billion Ponzi scheme was exposed, Congress authorized the SEC to award bounties from civil penalties recovered from securities law violators. It worked in a big way. In 2012, when the program started, the agency received more than 3,000 tips. By 2020, it had more than doubled, and it more than doubled again by 2023. The SEC now receives more than 50 tips per day, and the program has paid out a staggering $2 billion in bounty awards. According to the agency’s 2023 financial report, the SEC paid out nearly $600 million to whistleblowers last year.

The appeal of the whistleblower program is that it alerts the SEC to violations it may not otherwise uncover, without any additional staff. And since payouts are a percentage of fines collected, it costs the government little to implement.

Unfortunately, the program has resulted in a new industry of private de facto regulatory enforcers. Legal scholar Alexander Platt has shown how the SEC’s whistleblower program has effectively privatized a huge portion of financial regulatory enforcement. There is a role for publicly sourced information in securities regulatory enforcement, just as there has been in litigation for antitrust and other areas of the law. But the SEC program, and a similar one at the U.S. Commodity Futures Trading Commission, has created a market distortion replete with perverse incentives. Like the tax farmers of history, the interests of the whistleblowers don’t match those of the government.

First, while the blockbuster awards paid out to whistleblowers draw attention to the SEC’s successes, they obscure the fact that its staffing level has slightly declined during a period of tremendous market growth. In one case, the SEC’s largest ever, it paid $279 million to an individual whistleblower. That single award was nearly one-third of the funding of the SEC’s entire enforcement division last year. Congress gets to pat itself on the back for spinning up a program that pays for itself (by law, the SEC awards 10 to 30 percent of their penalty collections over $1 million to qualifying whistleblowers), when it should be talking about whether or not it’s given the agency enough resources to fulfill its mission to “maintain fair, orderly, and efficient markets.”

Second, while the stated purpose of the whistleblower program is to incentivize individuals to come forward with information about potential violations of securities law, this hasn’t actually led to increases in enforcement actions. Instead of legitimate whistleblowers bringing the most credible information to the SEC, the agency now seems to be deluged by tips that are not highly actionable.

But the biggest problem is that uncovering corporate malfeasance is now a legitimate business model, resulting in powerful firms and misaligned incentives. A single law practice led by former SEC assistant director Jordan Thomas captured about 20 percent of all the SEC’s whistleblower awards through 2022, at which point Thomas left to open up a new firm focused exclusively on whistleblowers. We can admire Thomas and his team’s impact on making those guilty of white-collar crimes pay, and also question whether hundreds of millions of dollars of penalties should be funneled through the hands of an SEC insider turned for-profit business mogul.

Whistleblower tips can be used as weapons of corporate warfare. SEC whistleblower complaints are not required to come from inside a company, or even to rely on insider information. They can be filed on the basis of public data, as long as the whistleblower brings original analysis. Companies might dig up dirt on their competitors and submit tips to the SEC. Ransomware groups have used the threat of SEC whistleblower tips as a tactic to pressure the companies they’ve infiltrated into paying ransoms.

The rise of whistleblower firms could lead to them taking particular “assignments” for a fee. Can a company hire one of these firms to investigate its competitors? Can an industry lobbying group under scrutiny (perhaps in cryptocurrencies) pay firms to look at other industries instead and tie up SEC resources? When a firm finds a potential regulatory violation, do they approach the company at fault and offer to cease their research for a “kill fee”? The lack of transparency and accountability of the program means that the whistleblowing firms can get away with practices like these, which would be wholly unacceptable if perpetrated by the SEC itself.

Whistleblowing firms can also use the information they uncover to guide market investments by activist short sellers. Since 2006, the investigative reporting site Sharesleuth claims to have tanked dozens of stocks and instigated at least eight SEC cases against companies in pharma, energy, logistics, and other industries, all after its investors shorted the stocks in question. More recently, a new investigative reporting site called Hunterbrook Media and partner hedge fund Hunterbrook Capital, have churned out 18 investigative reports in their first five months of operation and disclosed short sales and other actions alongside each. In at least one report, Hunterbrook says they filed an SEC whistleblower tip.

Short sellers carry an important disciplining function in markets. But combined with whistleblower awards, the same profit-hungry incentives can emerge. Properly staffed regulatory agencies don’t have the same potential pitfalls.

AI will affect every aspect of this dynamic. AI’s ability to extract information from large document troves will help whistleblowers provide more information to the SEC faster, lowering the bar for reporting potential violations and opening a floodgate of new tips. Right now, there is no cost to the whistleblower to report minor or frivolous claims; there is only cost to the SEC. While AI automation will also help SEC staff process tips more efficiently, it could exponentially increase the number of tips the agency has to deal with, further decreasing the efficiency of the program.

AI could be a triple windfall for those law firms engaged in this business: lowering their costs, increasing their scale, and increasing the SEC’s reliance on a few seasoned, trusted firms. The SEC already, as Platt documented, relies on a few firms to prioritize their investigative agenda. Experienced firms like Thomas’s might wield AI automation to the greatest advantage. SEC staff struggling to keep pace with tips might have less capacity to look beyond the ones seemingly pre-vetted by familiar sources.

But the real effects will be on the conflicts of interest between whistleblowing firms and the SEC. The ability to automate whistleblower reporting will open new competitive strategies that could disrupt business practices and market dynamics.

An AI-assisted data analyst could dig up potential violations faster, for a greater scale of competitor firms, and consider a greater scope of potential violations than any unassisted human could. The AI doesn’t have to be that smart to be effective here. Complaints are not required to be accurate; claims based on insufficient evidence could be filed against competitors, at scale.

Even more cynically, firms might use AI to help cover up their own violations. If a company can deluge the SEC with legitimate, if minor, tips about potential wrongdoing throughout the industry, it might lower the chances that the agency will get around to investigating the company’s own liabilities. Some companies might even use the strategy of submitting minor claims about their own conduct to obscure more significant claims the SEC might otherwise focus on.

Many of these ideas are not so new. There are decades of precedent for using algorithms to detect fraudulent financial activity, with lots of current-day application of the latest large language models and other AI tools. In 2019, legal scholar Dimitrios Kafteranis, research coordinator for the European Whistleblowing Institute, proposed using AI to automate corporate whistleblowing.

And not all the impacts specific to AI are bad. The most optimistic possible outcome is that AI will allow a broader base of potential tipsters to file, providing assistive support that levels the playing field for the little guy.

But more realistically, AI will supercharge the for-profit whistleblowing industry. The risks remain as long as submitting whistleblower complaints to the SEC is a viable business model. Like tax farming, the interests of the institutional whistleblower diverge from the interests of the state, and no amount of tweaking around the edges will make it otherwise.

Ultimately, AI is not the cause of or solution to the problems created by the runaway growth of the SEC whistleblower program. But it should give policymakers pause to consider the incentive structure that such programs create, and to reconsider the balance of public and private ownership of regulatory enforcement.

This essay was written with Nathan Sanders, and originally appeared in The American Prospect.

More on My AI and Democracy Book

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/more-on-my-ai-and-democracy-book.html

In July, I wrote about my new book project on AI and democracy, to be published by MIT Press in fall 2025. My co-author and collaborator Nathan Sanders and I are hard at work writing.

At this point, we would like feedback on titles. Here are four possibilities:

  1. Rewiring the Republic: How AI Will Transform our Politics, Government, and Citizenship
  2. The Thinking State: How AI Can Improve Democracy
  3. Better Run: How AI Can Make our Politics, Government, Citizenship More Efficient, Effective and Fair
  4. AI and the New Future of Democracy: Changes in Politics, Government, and Citizenship

What we want out of the title is that it convey (1) that it is a book about AI, (2) that it is a book about democracy writ large (and not just deepfakes), and (3) that it is largely optimistic.

What do you like? Feel free to do some mixing and matching: swapping “Will Transform” for “Will Improve” for “Can Transform” for “Can Improve,” for example. Or “Democracy” for “the Republic.” Remember, the goal here is for a title that will make a potential reader pick the book up off a shelf, or read the blurb text on a webpage. It needs to be something that will catch the reader’s attention. (Other title ideas are here).

Also, FYI, this is the current table of contents:

Introduction
1. Introduction: How AI will Change Democracy
2. Core AI Capabilities
3. Democracy as an Information System

Part I: AI-Assisted Politics
4. Background: Making Mistakes
5. Talking to Voters
6. Conducting Polls
7. Organizing a Political Campaign
8. Fundraising for Politics
9. Being a Politician

Part II: AI-Assisted Legislators
10. Background: Explaining Itself
11. Background: Who’s to Blame?
12. Listening to Constituents
13. Writing Laws
14. Writing More Complex Laws
15. Writing Laws that Empower Machines
16. Negotiating Legislation

Part III: The AI-Assisted Administration
17. Background: Exhibiting Values and Bias
18. Background: Augmenting Versus Replacing People
19. Serving People
20. Operating Government
21. Enforcing Regulations

Part IV: The AI-Assisted Court
22. Background: Being Fair
23. Background: Getting Hacked
24. Acting as a Lawyer
25. Arbitrating Disputes
26. Enforcing the Law
27. Reshaping Legislative Intent
28. Being a Judge

Part V: AI-Assisted Citizens
29. Background: AI and Power
30. Background: AI and Trust
31. Explaining the News
32. Watching the Government
33. Moderating, Facilitating, and Building Consensus
34. Acting as Your Personal Advocate
35. Acting as Your Personal Political Proxy

Part VI: Ensuring That AI Benefits Democracy
36. Why AI is Not Yet Good for Democracy
37. How to Ensure AI is Good for Democracy
38. What We Need to Do Now
39. Conclusion

Everything is subject to change, of course. The manuscript isn’t due to the publisher until the end of March, and who knows what AI developments will happen between now and then.

EDITED: The title under consideration is “Rewiring the Republic,” and not “Rewiring Democracy.” Although, I suppose, both are really under consideration.

Convert AWS console actions to reusable code with AWS Console-to-Code, now generally available

Post Syndicated from Abhishek Gupta original https://aws.amazon.com/blogs/aws/convert-aws-console-actions-to-reusable-code-with-aws-console-to-code-now-generally-available/

Today, we are announcing the general availability (GA) of AWS Console-to-Code that makes it easy to convert AWS console actions to reusable code. You can use AWS Console-to-Code to record your actions and workflows in the console, such as launching an Amazon Elastic Compute Cloud (Amazon EC2) instance, and review the AWS Command Line Interface (AWS CLI) commands for your console actions. With just a few clicks, Amazon Q can generate code for you using the infrastructure-as-code (IaC) format of your choice, including AWS CloudFormation template (YAML or JSON), and AWS Cloud Development Kit (AWS CDK) (TypeScript, Python or Java). This can be used as a starting point for infrastructure automation and further customized for your production workloads, included in pipelines, and more.

Since we announced the preview last year, AWS Console-to-Code has garnered positive response from customers. It has now been improved further in this GA version, because we have continued to work backwards from customer feedback.

New features in GA

  • Support for more services – During preview, the only supported service was Amazon EC2. At GA, AWS Console-to-Code has extended support to include Amazon Relational Database Service (RDS) and Amazon Virtual Private Cloud (Amazon VPC).
  • Simplified experience – The new user experience makes it easier for customers to manage the prototyping, recording and code generation workflows.
  • Preview code – The launch wizards for EC2 instances and Auto Scaling groups have been updated to allow customers to generate code for these resources without actually creating them.
  • Advanced code generation – AWS CDK and CloudFormation code generation is powered by Amazon Q machine learning models.

Getting started with AWS Console-to-Code
Let’s begin with a simple scenario of launching an Amazon EC2 instance. Start by accessing the Amazon EC2 console. Locate the AWS Console-to-Code widget on the right and choose Start recording to initiate the recording.

Now, launch an Amazon EC2 instance using the launch instance wizard in the Amazon EC2 console. After the instance is launched, choose Stop to complete the recording.

In the Recorded actions table, review the actions that were recorded. Use the Type dropdown list to filter by write actions (Write). Choose the RunInstances action. Select Copy CLI to copy the corresponding AWS CLI command.

This is the CLI command that I got from AWS Console-to-Code:

aws ec2 run-instances \
  --image-id "ami-066784287e358dad1" \
  --instance-type "t2.micro" \
  --network-interfaces '{"AssociatePublicIpAddress":true,"DeviceIndex":0,"Groups":["sg-1z1c11zzz1c11zzz1"]}' \
  --credit-specification '{"CpuCredits":"standard"}' \
  --tag-specifications '{"ResourceType":"instance","Tags":[{"Key":"Name","Value":"c2c-demo"}]}' \
  --metadata-options '{"HttpEndpoint":"enabled","HttpPutResponseHopLimit":2,"HttpTokens":"required"}' \
  --private-dns-name-options '{"HostnameType":"ip-name","EnableResourceNameDnsARecord":true,"EnableResourceNameDnsAAAARecord":false}' \
  --count "1"

This command can be easily modified. For this example, I updated it to launch two instances (--count 2) of type t3.micro (--instance-type). This is a simplified example, but the same technique can be applied to other workflows.

I executed the command using AWS CloudShell and it worked as expected, launching two t3.micro EC2 instances:

The single-click CLI code generation experience is based on the API commands that were used when actions were executed (while launching the EC2 instance). Its interesting to note that the companion screen surfaces recorded actions as you complete them in console. And thanks to the interactive UI with start and stop functionality, its easy to clearly scope actions for prototyping.

IaC generation using AWS CDK
AWS CDK is an open-source framework for defining cloud infrastructure in code and provisioning it through AWS CloudFormation. With AWS Console-to-Code, you can generate AWS CDK code (currently in Java, Python and TypeScript) for your infrastructure workflows.

Lets continue with the EC2 launch instance use case. If you haven’t done it already, in the Amazon EC2 console, locate the AWS Console-to-Code widget on the right, choose Start recording, and launch an EC2 instance. After the instance is launched, choose Stop to complete the recording and choose the RunInstances action from the Recorded actions table.

To generate AWS CDK Python code, choose the Generate CDK Python button from the dropdown list.

You can use the code as a starting point, customizing it to make it production-ready for your specific use case.

I already had the AWS CDK installed, so I created a new Python CDK project:

mkdir c2c_cdk_demo
cd c2c_cdk_demo
cdk init app --language python

Then, I plugged in the generated code in the Python CDK project. For this example, I refactored the code into a AWS CDK Stack, changed the EC2 instance type, and made other minor changes to ensure that the code was correct. I successfully deployed it using cdk deploy.

I was able to go from the console action to launch an EC2 instance and then all the way to AWS CDK to reproduce the same result.

from aws_cdk import (
    Stack,
    aws_ec2 as ec2,
)
from constructs import Construct

class MyProjectStack(Stack):

    def __init__(self, scope: Construct, construct_id: str, **kwargs) -> None:
        super().__init__(scope, construct_id, **kwargs)

        existing_vpc = ec2.Vpc.from_lookup(self, "ExistingVPC",
            is_default=True
        )

        instance = ec2.Instance(self, "Instance",
                instance_type=ec2.InstanceType("t3.micro"),
                machine_image=ec2.AmazonLinuxImage(),
                vpc=existing_vpc,
                vpc_subnets=ec2.SubnetSelection(
                    subnet_type=ec2.SubnetType.PUBLIC
                )
        )

You can also generate CloudFormation template in YAML or JSON format:

Preview code
You can also directly access AWS Console-to-Code from Preview code feature in Amazon EC2 and Amazon EC2 Auto Scaling group launch experience. This means that you don’t have to actually create the resource in order to get the infrastructure code.

To try this out, follow the steps to create an Auto Scaling group using a launch template. However, instead of Create Auto Scaling group, click Preview code. You should now see the options to generate infrastructure code or copy the AWS CLI command.

Things to know
Here are a few things you should consider while using AWS Console-to-Code:

  • Anyone can use AWS Console-to-Code to generate AWS CLI commands for their infrastructure workflows. The code generation feature for AWS CDK and CloudFormation formats has a free quota of 25 generations per month, after which you will need an Amazon Q Developer subscription.
  • It’s recommended that you test and verify the generated IaC code code before deployment.
  • At GA, AWS Console-to-Code only records actions in Amazon EC2, Amazon VPC and Amazon RDS consoles.
  • The Recorded actions table in AWS Console-to-Code only display actions taken during the current session within the specific browser tab, and it does not retain actions from previous sessions or other tabs. Note that refreshing the browser tab will result in the loss of all recorded actions.

Now available
AWS Console-to-Code is available in all commercial Regions. You can learn more about it in the Amazon EC2 documentation. Give it a try in the Amazon EC2 console and send feedback to the AWS re:Post for Amazon EC2 or through your usual AWS Support contacts.

Deebot Robot Vacuums Are Using Photos and Audio to Train Their AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/deebot-robot-vacuums-are-using-photos-and-audio-to-train-their-ai.html

An Australian news agency is reporting that robot vacuum cleaners from the Chinese company Deebot are surreptitiously taking photos and recording audio, and sending that data back to the vendor to train their AIs.

Ecovacs’s privacy policy—available elsewhere in the app—allows for blanket collection of user data for research purposes, including:

  • The 2D or 3D map of the user’s house generated by the device
  • Voice recordings from the device’s microphone
  • Photos or videos recorded by the device’s camera

It also states that voice recordings, videos and photos that are deleted via the app may continue to be held and used by Ecovacs.

No word on whether the recorded audio is being used to train the vacuum in some way, or whether it is being used to train a LLM.

Slashdot thread.

AWS Weekly Roundup: HIPAA eligible with Amazon Q Business, Amazon DCV, AWS re:Post Agent, and more (Oct 07, 2024)

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-q-business-is-hipaa-eligible-amazon-dcv-aws-repost-agent-and-more-oct-07-2024/

Last Friday, I had the privilege of attending China Engineer’s Day 2024(CED 2024) in Hangzhou as the Amazon Web Services (AWS) speaker. The event was organized by the China Computer Federation (CCF), one of the most influential professional developer communities in China.

At CED 2024, I spoke about how AI development tools can improve developer productivity. I was honored to receive a certificate of excellence from CCF, and Amazon Q garnered significant attention from the attendees.

Now, let’s turn to other exciting news in the AWS universe from last week.

Last week’s launches
Here are some launches that got my attention:

Amazon Q Business is now HIPAA eligible – Amazon Q business has received Health Insurance Portability and Accountability Act (HIPAA) certification. This means healthcare and life sciences organizations such as health insurance companies and healthcare providers can now use Amazon Q Business to run sensitive workloads regulated under the US HIPAA law.

NICE DCV renames to Amazon DCV – NICE DCV is rebranded to Amazon DCV. This high performance remote display protocol allows secure delivery of remote desktops and application streaming from any cloud or data center to any device, even over varying network conditions. Amazon DCV supports both Windows and major Linux distributions on the server side. Clients can use native DCV client for Windows, Linux, or macOS, as well as web browsers, to receive desktops and application streamings. The DCV server and client only transfer encrypted pixels, not data, ensuring no confidential information is downloaded. When using Amazon DCV on AWS with Amazon Elastic Compute Cloud (Amazon EC2), you can take advantage of the AWS 108 Availability Zones across the 33 geographic Regions and 31 local zones. The 2024.0 release now supports the latest Ubuntu 24.04 LTS. For more details, check out Sébastien Stormacq’s new launch blog post.

AWS re:Post launches re:Post Agent – AWS re:Post provides access to curated knowledge and a vibrant community that helps users become even more successful on AWS. re:Post Agent is a generative AI assistant designed to provide rapid, intelligent responses to questions in the re:Post community. It expands the available AWS knowledge base, and community experts will earn reputation points by reviewing the AI-generated answers.

Advanced configuration with Amazon Timestream for InfluxDB – This new launch introduces a feature that allows uses to monitor instance CPU, memory, and disk utilization metrics directly from the AWS Management Console.

A new stop ingestion API of Amazon Bedrock Knowledge Bases – This new API allows users to halt ongoing ingestion jobs at will. Providing greater control over data ingestion workflows, users can quickly stop accidental or unwanted ingestion processes without waiting for completion. By using the new StopIngestionJob API, you can respond rapidly to evolving needs and potentially reduce costs. This capability is available across all AWS Regions where Amazon Bedrock Knowledge Bases are offered.

Higher storage limit of Amazon AppStream 2.0 – Amazon AppStream 2.0 has expanded the default size limit for application settings persistence from 1 GB to 5 GB. This increase allows end users to store more application data and settings without manual intervention and without affecting performance or session setup time.

There were over 40 launches and releases last week. It was difficult for me to select the important ones. In addition to those already mentioned, here’s a list of potentially important feature updates:

For a full list of AWS announcements, be sure to keep an eye on AWS’s What’s New Feed page.

Other AWS news
Here are some other noteworthy items from last week.

Amazon WorkSpaces Thin Client – Amazon WorkSpaces Thin Client inventory is now available to purchase in the UK on Amazon Business, in addition to the US, France, Germany, Italy, and Spain. It’s a sleek, cost-effective device that brings secure access to AWS end user computing services right to your fingertips. This nifty gadget is like a digital fortress, preventing unauthorized data storage and applications, while giving IT admins the tools to manage and monitor their fleet of thin clients with ease.

Helping communities impacted by Hurricane Helene – AWS Disaster Response team is working closely with local partners and humanitarian organizations to deliver critical supplies to those in need in the Southeast. We’re also deploying AWS technology to help with re-connectivity, aid relief operations on the ground, and support food distribution needs in the region.

The life of a prescription at Amazon Pharmacy – Read the Amazon Pharmacy AI use case to remove the complexity of the process of dispensing medications and improve patients’ experiences. The system transcribes raw prescription data into standardized formats, transforms medical abbreviations into full-text equivalents, and validates medication details against an industry database. This automated process, followed by pharmacist review, has reduced potential medication errors by 50 percent and improved processing speed by up to 90 percent, allowing pharmacists to focus on critical tasks and personalized care.

A thought leadership article on generative AI in the WIRED magazine – Read Antje‘s news column in Wired. It discusses how AWS opens the transformative power of AI to organizations of any size and level of experience. I recommend it to all AI enthusiasts and business innovators. AWS is on a mission to bring generative AI magic to businesses of all sizes, offering a buffet of AI tools for tech wizards and newcomers alike. Whether you’re a startup with big dreams or a corporate giant looking to stay ahead, AWS is rolling out the red carpet to the AI revolution. Don’t miss this chance to turn your wildest tech fantasies into reality!

Upcoming AWS events
Check your calendars and sign up for these AWS events:

AWS re:Invent 2024 – Registration is now open for the annual tech extravaganza, taking place December 2 – 6 in Las Vegas. I’m eager to learn about the new launches and excited to contribute to two chalk talks focusing on security topics (Dev311 – Enhance code security with generative AI and SEC228 – Navigate multi-level protection scheme compliance in AWS China Regions).

AWS Innovate Migrate, Modernize, and Build – Whether you are new to the cloud or an experienced user, you will learn something new at AWS Innovate. This is a free online conference. Register at a time and region convenient to North America (October 15), or Europe, Middle East & Africa (October 24).

AWS Community Days – Join community-led conferences featuring technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world. Don’t miss out on the AWS Community Days happening on October 12 in Sofia and October 19 in Vadodara, Spain, and Guatemala.

Browse more upcoming AWS led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Betty

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

California AI Safety Bill Vetoed

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/california-ai-safety-bill-vetoed.html

Governor Newsom has vetoed the state’s AI safety bill.

I have mixed feelings about the bill. There’s a lot to like about it, and I want governments to regulate in this space. But, for now, it’s all EU.

(Related, the Council of Europe treaty on AI is ready for signature. It’ll be legally binding when signed, and it’s a big deal.)

Hacking ChatGPT by Planting False Memories into Its Data

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/10/hacking-chatgpt-by-planting-false-memories-into-its-data.html

This vulnerability hacks a feature that allows ChatGPT to have long-term memory, where it uses information from past conversations to inform future conversations with that same user. A researcher found that he could use that feature to plant “false memories” into that context window that could subvert the model.

A month later, the researcher submitted a new disclosure statement. This time, he included a PoC that caused the ChatGPT app for macOS to send a verbatim copy of all user input and ChatGPT output to a server of his choice. All a target needed to do was instruct the LLM to view a web link that hosted a malicious image. From then on, all input and output to and from ChatGPT was sent to the attacker’s website.

AWS Weekly Roundup: Jamba 1.5 family, Llama 3.2, Amazon EC2 C8g and M8g instances and more (Sep 30, 2024)

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-jamba-1-5-family-llama-3-2-amazon-ec2-c8g-and-m8g-instances-and-more-sep-30-2024/

Every week, there’s a new Amazon Web Services (AWS) community event where you can network, learn something new, and immerse yourself in the community. When you’re in a community, everyone grows together, and no one is left behind. Last week was no exception. I can highlight the Dutch AWS Community Day where Viktoria Semaan closed with a talk titled How to Create Impactful Content and Build a Strong Personal Brand, and the Peru User Group, who organized two days of talks and learning opportunities: UGCONF & SERVERLESSDAY 2024, featuring Jeff Barr, who spoke about how to Create Your Own Luck. The community events continue, so check them out at Upcoming AWS Community Days.

Last week’s launches
Here are the launches that got my attention.

Jamba 1.5 family of models by AI21 Labs is now available in Amazon Bedrock – The Jamba 1.5 Large and 1.5 Mini models feature a 256k context window, one of the longest on the market, enabling complex tasks like lengthy document analysis. With native support for structured JSON output, function calling, and document processing, they integrate into enterprise workflows for specialized AI solutions. To learn more, read Jamba 1.5 family of models by AI21 Labs is now available in Amazon Bedrock, visit the AI21 Labs in Amazon Bedrock page, and read the documentation.

AWS Lambda now supports Amazon Linux 2023 runtimes in AWS GovCloud (US) Regions – These runtimes offer the latest language features, including Python 3.12, Node.js 20, Java 21, .NET 8, Ruby 3.3, and Amazon Linux 2023. They have smaller deployment footprints, updated libraries, and a new package manager. Additionally, you can also use the container base images to build and deploy functions as a container image.

Amazon SageMaker Studio now supports automatic shutdown of idle applications – You can now enable automatic shutdown of inactive JupyterLab and CodeEditor applications using Amazon SageMaker Distribution image v2.0 or newer. Administrators can set idle shutdown times at domain or user profile levels, with optional user customization. This cost control mechanism helps avoid charges for unused instances and is available across all AWS Regions where SageMaker Studio is offered.

Amazon S3 is implementing a default 128 KB minimum object size for S3 Lifecycle transition rules to any S3 storage class – Reduce transition costs for datasets with many small objects by decreasing transition requests. Users can override the default and customize minimum object sizes. Existing rules remain unchanged, but the new default applies to new or modified configurations.

AWS Lake Formation centralized access control for Amazon Redshift data sharing is now available in 11 additional Regions – Enabling granular permissions management, including table, column, and row-level access to shared Amazon Redshift data. It also supports tag-based access control and trusted identity propagation with AWS IAM Identity Center for improved security and simplified management.

Llama 3.2 generative AI models now available in Amazon Bedrock – The collection includes 90B and 11B parameter multimodal models for sophisticated reasoning tasks, and 3B and 1B text-only models for edge devices. These models support vision tasks, offer improved performance, and are designed for responsible AI innovation across various applications. These models support a 128K context length and multilingual capabilities in eight languages. Learn more about it in Introducing Llama 3.2 models from Meta in Amazon Bedrock.

Share AWS End User Messaging SMS resources across multiple AWS accounts – You can use AWS Resource Access Manager (RAM), to share phone numbers, sender IDs, phone pools, and opt-out lists. Additionally, Amazon SNS now delivers SMS text messages through AWS End User Messaging, offering enhanced features like two-way messaging and granular permissions. These updates provide greater flexibility and control for SMS messaging across AWS services.

AWS Serverless Application Repository now supports AWS PrivateLink – Enabling direct connection from Amazon Virtual Private Cloud (VPC) without internet exposure. This enhances security by keeping communication within the AWS network. Available in all Regions where AWS Serverless Application Repository is offered, it can be set up using the AWS Management Console or AWS Command Line Interface (AWS CLI).

Amazon SageMaker with MLflow now supports AWS PrivateLink for secure traffic routing – Enabling secure data transfer from Amazon Virtual Private Cloud (VPC) to MLflow Tracking Servers within the AWS network. This enhances protection of sensitive information by avoiding public internet exposure. Available in most AWS Regions, it improves security for machine learning (ML) and generative AI experimentation using MLflow.

Introducing Amazon EC2 C8g and M8g Instances – Enhanced performance for compute-intensive and general-purpose workloads. With up to three times more vCPUs, three times more memory, 75 percent more memory bandwidth, and two times more L2 cache, these instances improve data processing, scalability, and cost-efficiency for various applications including high performance computing (HPC), batch processing, and microservices. Read more in Run your compute-
intensive and general purpose workloads sustainably with the new Amazon EC2 C8g, M8g instances.

Llama 3.2 models are now available in Amazon SageMaker JumpStart – These models offer various sizes from 1B to 90B parameters, support multimodal tasks, including image reasoning, and are more efficient for AI workloads. The 1B and 3B models can be fine-tuned, while Llama Guard 3 11B Vision supports responsible innovation and system-level safety. Learn more in Llama 3.2 models from Meta are now available in Amazon SageMaker JumpStart.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS news
Here are some additional projects, blog posts, and news items that you might find interesting:

Deploy generative AI agents in your contact center for voice and chat using Amazon Connect, Amazon Lex, and Amazon Bedrock Knowledge Bases – This solution enables low-latency customer interactions, answering queries from a knowledge base. Features include conversation analytics, automated testing, and hallucination detection in a serverless architecture.

How AWS WAF threat intelligence features help protect the player experience for betting and gaming customers – AWS WAF enhances bot protection for betting and gaming. New features include browser fingerprinting, automation detection, and ML models to identify coordinated bots. These tools combat scraping, fraud, distributed denial of service (DDoS) attacks, and cheating, safeguarding player experiences.

How to migrate 3DES keys from a FIPS to a non-FIPS AWS CloudHSM cluster – Learn how to securely transfer Triple Data Encryption Algorithm (3DES) keys from Federal Information Processing Standard (FIPS) hsm1 to non-FIPS hsm2 clusters using RSA-AES wrapping, without backups. This enables using new hsm2.medium instances with FIPS 140-3 Level 3 support, non-FIPS mode, increased key capacity, and mutual TLS (mTLS).

Upcoming AWS events
Check your calendars and sign up for upcoming AWS events:

AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. These events offer technical sessions, demonstrations, and workshops delivered by experts. There is only one event left that you can still register for: Ottawa (October 9).

AWS Community Days – Join community-led conferences featuring technical discussions, workshops, and hands-on labs driven by expert AWS users and industry leaders from around the world. Upcoming AWS Community Days are scheduled for October 3 in the Netherlands and Romania, and on October 5 in Jaipur, Mexico, Bolivia, Ecuador, and Panama. I’m happy to share with you that I will be joining the Panama community on October 5.

AWS GenAI Lofts – Collaborative spaces and immersive experiences that showcase AWS’s expertise with the cloud and AI, while providing startups and developers with hands-on access to AI products and services, exclusive sessions with industry leaders, and valuable networking opportunities with investors and peers. Find a GenAI Loft location near you and don’t forget to register. I’ll be in the San Francisco lounge with some demos on October 15 at the Gen AI Developer Day. If you’re attending, feel free to stop by and say hello!

Browse all upcoming AWS led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

Thanks to Dmytro Hlotenko and Diana Alfaro for the photos of their community events.

— Eli

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

AI and the 2024 US Elections

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/09/ai-and-the-2024-us-elections.html

For years now, AI has undermined the public’s ability to trust what it sees, hears, and reads. The Republican National Committee released a provocative ad offering an “AI-generated look into the country’s possible future if Joe Biden is re-elected,” showing apocalyptic, machine-made images of ruined cityscapes and chaos at the border. Fake robocalls purporting to be from Biden urged New Hampshire residents not to vote in the 2024 primary election. This summer, the Department of Justice cracked down on a Russian bot farm that was using AI to impersonate Americans on social media, and OpenAI disrupted an Iranian group using ChatGPT to generate fake social-media comments.

It’s not altogether clear what damage AI itself may cause, though the reasons for concern are obvious—the technology makes it easier for bad actors to construct highly persuasive and misleading content. With that risk in mind, there has been some movement toward constraining the use of AI, yet progress has been painstakingly slow in the area where it may count most: the 2024 election.

Two years ago, the Biden administration issued a blueprint for an AI Bill of Rights aiming to address “unsafe or ineffective systems,” “algorithmic discrimination,” and “abusive data practices,” among other things. Then, last year, Biden built on that document when he issued his executive order on AI. Also in 2023, Senate Majority Leader Chuck Schumer held an AI summit in Washington that included the centibillionaires Bill Gates, Mark Zuckerberg, and Elon Musk. Several weeks later, the United Kingdom hosted an international AI Safety Summit that led to the serious-sounding “Bletchley Declaration,” which urged international cooperation on AI regulation. The risks of AI fakery in elections have not sneaked up on anybody.

Yet none of this has resulted in changes that would resolve the use of AI in U.S. political campaigns. Even worse, the two federal agencies with a chance to do something about it have punted the ball, very likely until after the election.

On July 25, the Federal Communications Commission issued a proposal that would require political advertisements on TV and radio to disclose if they used AI. (The FCC has no jurisdiction over streaming, social media, or web ads.) That seems like a step forward, but there are two big problems. First, the proposed rules, even if enacted, are unlikely to take effect before early voting starts in this year’s election. Second, the proposal immediately devolved into a partisan slugfest. A Republican FCC commissioner alleged that the Democratic National Committee was orchestrating the rule change because Democrats are falling behind the GOP in using AI in elections. Plus, he argued, this was the Federal Election Commission’s job to do.

Yet last month, the FEC announced that it won’t even try making new rules against using AI to impersonate candidates in campaign ads through deepfaked audio or video. The FEC also said that it lacks the statutory authority to make rules about misrepresentations using deepfaked audio or video. And it lamented that it lacks the technical expertise to do so, anyway. Then, last week, the FEC compromised, announcing that it intends to enforce its existing rules against fraudulent misrepresentation regardless of what technology it is conducted with. Advocates for stronger rules on AI in campaign ads, such as Public Citizen, did not find this nearly sufficient, characterizing it as a “wait-and-see approach” to handling “electoral chaos.”

Perhaps this is to be expected: The freedom of speech guaranteed by the First Amendment generally permits lying in political ads. But the American public has signaled that it would like some rules governing AI’s use in campaigns. In 2023, more than half of Americans polled responded that the federal government should outlaw all uses of AI-generated content in political ads. Going further, in 2024, about half of surveyed Americans said they thought that political candidates who intentionally manipulated audio, images, or video should be prevented from holding office or removed if they had won an election. Only 4 percent thought there should be no penalty at all.

The underlying problem is that Congress has not clearly given any agency the responsibility to keep political advertisements grounded in reality, whether in response to AI or old-fashioned forms of disinformation. The Federal Trade Commission has jurisdiction over truth in advertising, but political ads are largely exempt—again, part of our First Amendment tradition. The FEC’s remit is campaign finance, but the Supreme Court has progressively stripped its authorities. Even where it could act, the commission is often stymied by political deadlock. The FCC has more evident responsibility for regulating political advertising, but only in certain media: broadcast, robocalls, text messages. Worse yet, the FCC’s rules are not exactly robust. It has actually loosened rules on political spam over time, leading to the barrage of messages many receive today. (That said, in February, the FCC did unanimously rule that robocalls using AI voice-cloning technology, like the Biden ad in New Hampshire, are already illegal under a 30-year-old law.)

It’s a fragmented system, with many important activities falling victim to gaps in statutory authority and a turf war between federal agencies. And as political campaigning has gone digital, it has entered an online space with even fewer disclosure requirements or other regulations. No one seems to agree where, or whether, AI is under any of these agencies’ jurisdictions. In the absence of broad regulation, some states have made their own decisions. In 2019, California was the first state in the nation to prohibit the use of deceptively manipulated media in elections, and has strengthened these protections with a raft of newly passed laws this fall. Nineteen states have now passed laws regulating the use of deepfakes in elections.

One problem that regulators have to contend with is the wide applicability of AI: The technology can simply be used for many different things, each one demanding its own intervention. People might accept a candidate digitally airbrushing their photo to look better, but not doing the same thing to make their opponent look worse. We’re used to getting personalized campaign messages and letters signed by the candidate; is it okay to get a robocall with a voice clone of the same politician speaking our name? And what should we make of the AI-generated campaign memes now shared by figures such as Musk and Donald Trump?

Despite the gridlock in Congress, these are issues with bipartisan interest. This makes it conceivable that something might be done, but probably not until after the 2024 election and only if legislators overcome major roadblocks. One bill under consideration, the AI Transparency in Elections Act, would instruct the FEC to require disclosure when political advertising uses media generated substantially by AI. Critics say, implausibly, that the disclosure is onerous and would increase the cost of political advertising. The Honest Ads Act would modernize campaign-finance law, extending FEC authority to definitively encompass digital advertising. However, it has languished for years because of reported opposition from the tech industry. The Protect Elections From Deceptive AI Act would ban materially deceptive AI-generated content from federal elections, as in California and other states. These are promising proposals, but libertarian and civil-liberties groups are already signaling challenges to all of these on First Amendment grounds. And, vexingly, at least one FEC commissioner has directly cited congressional consideration of some of these bills as a reason for his agency not to act on AI in the meantime.

One group that benefits from all this confusion: tech platforms. When few or no evident rules govern political expenditures online and uses of new technologies like AI, tech companies have maximum latitude to sell ads, services, and personal data to campaigns. This is reflected in their lobbying efforts, as well as the voluntary policy restraints they occasionally trumpet to convince the public they don’t need greater regulation.

Big Tech has demonstrated that it will uphold these voluntary pledges only if they benefit the industry. Facebook once, briefly, banned political advertising on its platform. No longer; now it even allows ads that baselessly deny the outcome of the 2020 presidential election. OpenAI’s policies have long prohibited political campaigns from using ChatGPT, but those restrictions are trivial to evade. Several companies have volunteered to add watermarks to AI-generated content, but they are easily circumvented. Watermarks might even make disinformation worse by giving the false impression that non-watermarked images are legitimate.

This important public policy should not be left to corporations, yet Congress seems resigned not to act before the election. Schumer hinted to NBC News in August that Congress may try to attach deepfake regulations to must-pass funding or defense bills this month to ensure that they become law before the election. More recently, he has pointed to the need for action “beyond the 2024 election.”

The three bills listed above are worthwhile, but they are just a start. The FEC and FCC should not be left to snipe with each other about what territory belongs to which agency. And the FEC needs more significant, structural reform to reduce partisan gridlock and enable it to get more done. We also need transparency into and governance of the algorithmic amplification of misinformation on social-media platforms. That requires that the pervasive influence of tech companies and their billionaire investors should be limited through stronger lobbying and campaign-finance protections.

Our regulation of electioneering never caught up to AOL, let alone social media and AI. And deceiving videos harm our democratic process, whether they are created by AI or actors on a soundstage. But the urgent concern over AI should be harnessed to advance legislative reform. Congress needs to do more than stick a few fingers in the dike to control the coming tide of election disinformation. It needs to act more boldly to reshape the landscape of regulation for political campaigning.

This essay was written with Nathan Sanders, and originally appeared in The Atlantic.

Introducing Llama 3.2 models from Meta in Amazon Bedrock: A new generation of multimodal vision and lightweight models

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/introducing-llama-3-2-models-from-meta-in-amazon-bedrock-a-new-generation-of-multimodal-vision-and-lightweight-models/

In July, we announced the availability of Llama 3.1 models in Amazon Bedrock. Generative AI technology is improving at incredible speed and today, we are excited to introduce the new Llama 3.2 models from Meta in Amazon Bedrock.

Llama 3.2 offers multimodal vision and lightweight models representing Meta’s latest advancement in large language models (LLMs) and providing enhanced capabilities and broader applicability across various use cases. With a focus on responsible innovation and system-level safety, these new models demonstrate state-of-the-art performance on a wide range of industry benchmarks and introduce features that help you build a new generation of AI experiences.

These models are designed to inspire builders with image reasoning and are more accessible for edge applications, unlocking more possibilities with AI.

The Llama 3.2 collection of models are offered in various sizes, from lightweight text-only 1B and 3B parameter models suitable for edge devices to small and medium-sized 11B and 90B parameter models capable of sophisticated reasoning tasks including multimodal support for high resolution images. Llama 3.2 11B and 90B are the first Llama models to support vision tasks, with a new model architecture that integrates image encoder representations into the language model. The new models are designed to be more efficient for AI workloads, with reduced latency and improved performance, making them suitable for a wide range of applications.

All Llama 3.2 models support a 128K context length, maintaining the expanded token capacity introduced in Llama 3.1. Additionally, the models offer improved multilingual support for eight languages including English, German, French, Italian, Portuguese, Hindi, Spanish, and Thai.

In addition to the existing text capable Llama 3.1 8B, 70B, and 405B models, Llama 3.2 supports multimodal use cases. You can now use four new Llama 3.2 models — 90B, 11B, 3B, and 1B — from Meta in Amazon Bedrock to build, experiment, and scale your creative ideas:

Llama 3.2 90B Vision (text + image input) – Meta’s most advanced model, ideal for enterprise-level applications. This model excels at general knowledge, long-form text generation, multilingual translation, coding, math, and advanced reasoning. It also introduces image reasoning capabilities, allowing for image understanding and visual reasoning tasks. This model is ideal for the following use cases: image captioning, image-text retrieval, visual grounding, visual question answering and visual reasoning, and document visual question answering.

Llama 3.2 11B Vision (text + image input) – Well-suited for content creation, conversational AI, language understanding, and enterprise applications requiring visual reasoning. The model demonstrates strong performance in text summarization, sentiment analysis, code generation, and following instructions, with the added ability to reason about images. This model use cases are similar to the 90B version: image captioning, image-text-retrieval, visual grounding, visual question answering and visual reasoning, and document visual question answering.

Llama 3.2 3B (text input) – Designed for applications requiring low-latency inferencing and limited computational resources. It excels at text summarization, classification, and language translation tasks. This model is ideal for the following use cases: mobile AI-powered writing assistants and customer service applications.

Llama 3.2 1B (text input) – The most lightweight model in the Llama 3.2 collection of models, perfect for retrieval and summarization for edge devices and mobile applications. This model is ideal for the following use cases: personal information management and multilingual knowledge retrieval.

In addition, Llama 3.2 is built on top of the Llama Stack, a standardized interface for building canonical toolchain components and agentic applications, making building and deploying easier than ever. Llama Stack API adapters and distributions are designed to most effectively leverage the Llama model capabilities and it gives customers the ability to benchmark Llama models across different vendors.

Meta has tested Llama 3.2 on over 150 benchmark datasets spanning multiple languages and conducted extensive human evaluations, demonstrating competitive performance with other leading foundation models. Let’s see how these models work in practice.

Using Llama 3.2 models in Amazon Bedrock
To get started with Llama 3.2 models, I navigate to the Amazon Bedrock console and choose Model access on the navigation pane. There, I request access for the new Llama 3.2 models: Llama 3.2 1B, 3B, 11B Vision, and 90B Vision.

To test the new vision capability, I open another browser tab and download from the Our World in Data website the Share of electricity generated by renewables chart in PNG format. The chart is very high resolution and I resize it to be 1024 pixel wide.

Back in the Amazon Bedrock console, I choose Chat under Playgrounds in the navigation pane, select Meta as the category, and choose the Llama 3.2 90B Vision model.

I use Choose files to select the resized chart image and use this prompt:

Based on this chart, which countries in Europe have the highest share?

I choose Run and the model analyzes the image and returns its results:

Using Meta Llama 3.2 models in the Amazon Bedrock console

I can also access the models programmatically using the AWS Command Line Interface (AWS CLI) and AWS SDKs. Compared to using the Llama 3.1 models, I only need to update the model IDs as described in the documentation. I can also use the new cross-region inference endpoint for the US and the EU Regions. These endpoints work for any Region within the US and the EU respectively. For example, the cross-region inference endpoints for the Llama 3.2 90B Vision model are:

  • us.meta.llama3-2-90b-instruct-v1:0
  • eu.meta.llama3-2-90b-instruct-v1:0

Here’s a sample AWS CLI command using the Amazon Bedrock Converse API. I use the --query parameter of the CLI to filter the result and only show the text content of the output message:

aws bedrock-runtime converse --messages '[{ "role": "user", "content": [ { "text": "Tell me the three largest cities in Italy." } ] }]' --model-id us.meta.llama3-2-90b-instruct-v1:0 --query 'output.message.content[*].text' --output text

In output, I get the response message from the "assistant".

The three largest cities in Italy are:

1. Rome (Roma) - population: approximately 2.8 million
2. Milan (Milano) - population: approximately 1.4 million
3. Naples (Napoli) - population: approximately 970,000

It’s not much different if you use one of the AWS SDKs. For example, here’s how you can use Python with the AWS SDK for Python (Boto3) to analyze the same image as in the console example:

import boto3

MODEL_ID = "us.meta.llama3-2-90b-instruct-v1:0"
# MODEL_ID = "eu.meta.llama3-2-90b-instruct-v1:0"

IMAGE_NAME = "share-electricity-renewable-small.png"

bedrock_runtime = boto3.client("bedrock-runtime")

with open(IMAGE_NAME, "rb") as f:
    image = f.read()

user_message = "Based on this chart, which countries in Europe have the highest share?"

messages = [
    {
        "role": "user",
        "content": [
            {"image": {"format": "png", "source": {"bytes": image}}},
            {"text": user_message},
        ],
    }
]

response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=messages,
)
response_text = response["output"]["message"]["content"][0]["text"]
print(response_text)

Llama 3.2 models are also available in Amazon SageMaker JumpStart, a machine learning (ML) hub that makes it easy to deploy pre-trained models using the console or programmatically through the SageMaker Python SDK. From SageMaker JumpStart, you can also access and deploy new safeguard models that can help classify the safety level of model inputs (prompts) and outputs (responses), including Llama Guard 3 11B Vision, which are designed to support responsible innovation and system-level safety.

In addition, you can easily fine-tune Llama 3.2 1B and 3B models with SageMaker JumpStart today. Fine-tuned models can then be imported as custom models into Amazon Bedrock. Fine-tuning for the full collection of Llama 3.2 models in Amazon Bedrock and Amazon SageMaker JumpStart is coming soon.

The publicly available weights of Llama 3.2 models make it easier to deliver tailored solutions for custom needs. For example, you can fine-tune a Llama 3.2 model for a specific use case and bring it into Amazon Bedrock as a custom model, potentially outperforming other models in domain-specific tasks. Whether you’re fine-tuning for enhanced performance in areas like content creation, language understanding, or visual reasoning, Llama 3.2’s availability in Amazon Bedrock and SageMaker empowers you to create unique, high-performing AI capabilities that can set your solutions apart.

More on Llama 3.2 model architecture
Llama 3.2 builds upon the success of its predecessors with an advanced architecture designed for optimal performance and versatility:

Auto-regressive language model – At its core, Llama 3.2 uses an optimized transformer architecture, allowing it to generate text by predicting the next token based on the previous context.

Fine-tuning techniques – The instruction-tuned versions of Llama 3.2 employ two key techniques:

  • Supervised fine-tuning (SFT) – This process adapts the model to follow specific instructions and generate more relevant responses.
  • Reinforcement learning with human feedback (RLHF) – This advanced technique aligns the model’s outputs with human preferences, enhancing helpfulness and safety.

Multimodal capabilities – For the 11B and 90B Vision models, Llama 3.2 introduces a novel approach to image understanding:

  • Separately trained image reasoning adaptor weights are integrated with the core LLM weights.
  • These adaptors are connected to the main model through cross-attention mechanisms. Cross-attention allows one section of the model to focus on relevant parts of another component’s output, enabling information flow between different sections of the model.
  • When an image is input, the model treats the image reasoning process as a “tool use” operation, allowing for sophisticated visual analysis alongside text processing. In this context, tool use is the generic term used when a model uses external resources or functions to augment its capabilities and complete tasks more effectively.

Optimized inference – All models support grouped-query attention (GQA), which enhances inference speed and efficiency, particularly beneficial for the larger 90B model.

This architecture enables Llama 3.2 to handle a wide range of tasks, from text generation and understanding to complex reasoning and image analysis, all while maintaining high performance and adaptability across different model sizes.

Things to know
Llama 3.2 models from Meta are now generally available in Amazon Bedrock in the following AWS Regions:

  • Llama 3.2 1B and 3B models are available in the US West (Oregon) and Europe (Frankfurt) Regions, and are available in the US East (Ohio, N. Virginia) and Europe (Ireland, Paris) Regions via cross-region inference.
  • Llama 3.2 11B Vision and 90B Vision models are available in the US West (Oregon) Region, and are available in the US East (Ohio, N. Virginia) Regions via cross-region inference.

Check the full AWS Region list for future updates. To estimate your costs, visit the Amazon Bedrock pricing page.

To learn more about Llama 3.2 features and capabilities, visit the Llama models section of the Amazon Bedrock documentation. Give Llama 3.2 a try in the Amazon Bedrock console today, and send feedback to AWS re:Post for Amazon Bedrock.

You can find deep-dive technical content and discover how our Builder communities are using Amazon Bedrock at community.aws. Let us know what you build with Llama 3.2 in Amazon Bedrock!

— Danilo

Jamba 1.5 family of models by AI21 Labs is now available in Amazon Bedrock

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/jamba-1-5-family-of-models-by-ai21-labs-is-now-available-in-amazon-bedrock/

Today, we are announcing the availability of AI21 Labs’ powerful new Jamba 1.5 family of large language models (LLMs) in Amazon Bedrock. These models represent a significant advancement in long-context language capabilities, delivering speed, efficiency, and performance across a wide range of applications. The Jamba 1.5 family of models includes Jamba 1.5 Mini and Jamba 1.5 Large. Both models support a 256K token context window, structured JSON output, function calling, and are capable of digesting document objects.

AI21 Labs is a leader in building foundation models and artificial intelligence (AI) systems for the enterprise. Together, AI21 Labs and AWS are empowering customers across industries to build, deploy, and scale generative AI applications that solve real-world challenges and spark innovation through a strategic collaboration. With AI21 Labs’ advanced, production-ready models together with Amazon’s dedicated services and powerful infrastructure, customers can leverage LLMs in a secure environment to shape the future of how we process information, communicate, and learn.

What is Jamba 1.5?
Jamba 1.5 models leverage a unique hybrid architecture that combines the transformer model architecture with Structured State Space model (SSM) technology. This innovative approach allows Jamba 1.5 models to handle long context windows up to 256K tokens, while maintaining the high-performance characteristics of traditional transformer models. You can learn more about this hybrid SSM/transformer architecture in the Jamba: A Hybrid Transformer-Mamba Language Model whitepaper.

You can now use two new Jamba 1.5 models from AI21 in Amazon Bedrock:

  • Jamba 1.5 Large excels at complex reasoning tasks across all prompt lengths, making it ideal for applications that require high quality outputs on both long and short inputs.
  • Jamba 1.5 Mini is optimized for low-latency processing of long prompts, enabling fast analysis of lengthy documents and data.

Key strengths of the Jamba 1.5 models include:

  • Long context handling – With 256K token context length, Jamba 1.5 models can improve the quality of enterprise applications, such as lengthy document summarization and analysis, as well as agentic and RAG workflows.
  • Multilingual – Support for English, Spanish, French, Portuguese, Italian, Dutch, German, Arabic, and Hebrew.
  • Developer-friendly – Native support for structured JSON output, function calling, and capable of digesting document objects.
  • Speed and efficiency – AI21 measured the performance of Jamba 1.5 models and shared that the models demonstrate up to 2.5X faster inference on long contexts than other models of comparable sizes. For detailed performance results, visit the Jamba model family announcement on the AI21 website.

Get started with Jamba 1.5 models in Amazon Bedrock
To get started with the new Jamba 1.5 models, go to the Amazon Bedrock console, choose Model access on the bottom left pane, and request access to Jamba 1.5 Mini or Jamba 1.5 Large.

Amazon Bedrock - Model access to AI21 Jamba 1.5 models

To test the Jamba 1.5 models in the Amazon Bedrock console, choose the Text or Chat playground in the left menu pane. Then, choose Select model and select AI21 as the category and Jamba 1.5 Mini or Jamba 1.5 Large as the model.

Jamba 1.5 in the Amazon Bedrock text playground

By choosing View API request, you can get a code example of how to invoke the model using the AWS Command Line Interface (AWS CLI) with the current example prompt.

You can follow the code examples in the Amazon Bedrock documentation to access available models using AWS SDKs and to build your applications using various programming languages.

The following Python code example shows how to send a text message to Jamba 1.5 models using the Amazon Bedrock Converse API for text generation.

import boto3
from botocore.exceptions import ClientError

# Create a Bedrock Runtime client.
bedrock_runtime = boto3.client("bedrock-runtime", region_name="us-east-1")

# Set the model ID.
# modelId = "ai21.jamba-1-5-mini-v1:0"
model_id = "ai21.jamba-1-5-large-v1:0"

# Start a conversation with the user message.
user_message = "What are 3 fun facts about mambas?"
conversation = [
    {
        "role": "user",
        "content": [{"text": user_message}],
    }
]

try:
    # Send the message to the model, using a basic inference configuration.
    response = bedrock_runtime.converse(
        modelId=model_id,
        messages=conversation,
        inferenceConfig={"maxTokens": 256, "temperature": 0.7, "topP": 0.8},
    )

    # Extract and print the response text.
    response_text = response["output"]["message"]["content"][0]["text"]
    print(response_text)

except (ClientError, Exception) as e:
    print(f"ERROR: Can't invoke '{model_id}'. Reason: {e}")
    exit(1)

The Jamba 1.5 models are perfect for use cases like paired document analysis, compliance analysis, and question answering for long documents. They can easily compare information across multiple sources, check if passages meet specific guidelines, and handle very long or complex documents. You can find example code in the AI21-on-AWS GitHub repo. To learn more about how to prompt Jamba models effectively, check out AI21’s documentation.

Now available
AI21 Labs’ Jamba 1.5 family of models is generally available today in Amazon Bedrock in the US East (N. Virginia) AWS Region. Check the full Region list for future updates. To learn more, check out the AI21 Labs in Amazon Bedrock product page and pricing page.

Give Jamba 1.5 models a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

Visit our community.aws site to find deep-dive technical content and to discover how our Builder communities are using Amazon Bedrock in their solutions.

— Antje

Hello World #25 out now: Generative AI

Post Syndicated from Meg Wang original https://www.raspberrypi.org/blog/hello-world-25-out-now-generative-ai/

Since they became publicly available at the end of 2022, generative AI tools have been hotly discussed by educators: what role should these tools for generating human-seeming text, images, and other media play in teaching and learning?

Two years later, the one thing most people agree on is that, like it or not, generative AI is here to stay. And as a computing educator, you probably have your learners and colleagues looking to you for guidance about this technology. We’re sharing how educators like you are approaching generative AI in issue 25 of Hello World, out today for free.

Digital image of a copy of Hello World magazine, issue 25.

Generative AI and teaching

Since our ‘Teaching and AI’ issue a year ago, educators have been making strides grappling with generative AI’s place in their classroom, and with the potential risks to young people. In this issue, you’ll hear from a wide range of educators who are approaching this technology in different ways. 

For example:

  • Laura Ventura from Gwinnett County Public Schools (GCPS) in Georgia, USA shares how the GCPS team has integrated AI throughout their K–12 curriculum
  • Mark Calleja from our team guides you through using the OCEAN prompt process to reliably get the results you want from an LLM 
  • Kip Glazer, principal at Mountain View High School in California, USA shares a framework for AI implementation aimed at school leaders
  • Stefan Seegerer, a researcher and educator in Germany, discusses why unplugged activities help us focus on what’s really important in teaching about AI

This issue also includes practical solutions to problems that are unique to computer science educators:

  • Graham Hastings in the UK shares his solution to tricky crocodile clips when working with micro:bits
  • Riyad Dhuny shares his case study of home-hosting a learning management system with his students in Mauritius

And there is lots more for you to discover in issue 25.

Whether or not you use generative AI as part of your teaching practice, it’s important for you to be aware of AI technologies and how your young people may be interacting with it. In his article “A problem-first approach to the development of AI systems”, Ben Garside from our team affirms that:

“A big part of our job as educators is to help young people navigate the changing world and prepare them for their futures, and education has an essential role to play in helping people understand AI technologies so that they can avoid the dangers.

Our approach at the Raspberry Pi Foundation is not to focus purely on the threats and dangers, but to teach young people to be critical users of technologies and not passive consumers. […]

Our call to action to educators, carers, and parents is to have conversations with your young people about generative AI. Get to know their opinions on it and how they view its role in their lives, and help them to become critical thinkers when interacting with technology.”

Share your thoughts & subscribe to Hello World

Computing teachers are being asked again to teach something that they didn’t study. With generative AI as with all things computing, we want to support your teaching and share your successes. We hope you enjoy this issue of Hello World, and please get in touch with your article ideas or what you would like to see in the magazine.


We’d like to thank Oracle for supporting this issue.

The post Hello World #25 out now: Generative AI appeared first on Raspberry Pi Foundation.