Tag Archives: open source

Git’s database internals II: commit history queries

Post Syndicated from Derrick Stolee original https://github.blog/2022-08-30-gits-database-internals-ii-commit-history-queries/

This week, we are exploring Git’s internals with the following concept in mind:

Git is the distributed database at the core of your engineering system.

Git’s role as a version control system has multiple purposes. One is to help your team make collaborative changes to a common repository. Another purpose is to allow individuals to search and investigate the history of the repository. These history investigations form an interesting query type when thinking of Git as a database.

Not only are history queries an interesting query type, but Git commit history presents interesting data shapes that inform how Git’s algorithms satisfy those queries.

Let’s dig into some common history queries now.

Git history queries

History queries can take several forms. For this post, we are focused only on history queries based entirely on the commits themselves. In part III we will explore file history queries.

Recent commits

Users most frequently interact with commit history using git log to see the latest changes in the current branch. git log shows the commit history which relies on starting at some known commits and then visiting their parent commits and continuing to “walk” parent relationships until all interesting commits are shown to the user. This command can be modified to compare the commits in different branches or display commits in a graphical visualization.

$ git log --oneline --graph 091680472db
* 091680472db Merge branch 'tb/midx-race-in-pack-objects'
|\
| * 4090511e408 builtin/pack-objects.c: ensure pack validity from MIDX bitmap objects
| * 5045759de85 builtin/pack-objects.c: ensure included `--stdin-packs` exist
| * 58a6abb7bae builtin/pack-objects.c: avoid redundant NULL check
| * 44f9fd64967 pack-bitmap.c: check preferred pack validity when opening MIDX bitmap
* | d8c8dccbaaf Merge branch 'ds/object-file-unpack-loose-header-fix'
|\ \
| * | 8a50571a0ea object-file: convert 'switch' back to 'if'
* | | a9e7c3a6efe Merge branch 'pb/use-freebsd-12.3-in-cirrus-ci'
|\ \ \
| * | | c58bebd4c67 ci: update Cirrus-CI image to FreeBSD 12.3
| | |/
| |/|
* | | b3b2ddced29 Merge branch 'ds/bundle-uri'
|\ \ \
| * | | 89c6e450fe4 bundle.h: make "fd" version of read_bundle_header() public
| * | | 834e3520ab6 remote: allow relative_url() to return an absolute url

Containment queries

We sometimes also need to get extra information about our commit history, such as asking “which tags contain this commit?” The git tag --contains command is one way to answer that question.

$ git tag --contains 4ae3003ba5
v2.36.0
v2.36.0-rc0
v2.36.0-rc1
v2.36.0-rc2
v2.36.1
v2.37.0
v2.37.0-rc0
v2.37.0-rc1
v2.37.0-rc2

The similar git branch --contains command will report all branches that can reach a given commit. These queries can be extremely valuable. For example, they can help identify which versions of a product have a given bugfix.

Merge base queries

When creating a merge commit, Git uses a three-way merge algorithm to automatically resolve the differences between the two independent commits being merged. As the name implies, a third commit is required: a merge base.

A merge base between two commits is a commit that is in the history of both commits. Technically, any commit in their common history is sufficient, but the three-way merge algorithm works better if the difference between the merge base and each side of the merge is as small as possible.

Git tries to select a single merge base that is not reachable from any other potential merge base. While this choice is usually unique, certain commit histories can permit multiple “best” merge bases, in which case Git prints all of them.

The git merge-base command takes two commits and outputs the object ID of the merge base commit that satisfies all of the properties described earlier.

$ git merge-base 3d8e3dc4fc d02cc45c7a
3d8e3dc4fc22fe41f8ee1184f085c600f35ec76f

One thing that can help to visualize merge commits is to explore the boundary between two commit histories. When considering the commit range B..A, a commit C is on the boundary if it is reachable from both A and B and there is at least one commit that is reachable from A and not reachable from B and has C as its parent. In this way, the boundary commits are the commits in the common history that are parents of something in the symmetric difference. There are a number of commits on the boundary of these two example commits, but one of them can reach all of the others providing the unique choice in merge base.

$ git log --graph --oneline --boundary 3d8e3dc4fc..d02cc45c7a
* d02cc45c7a2c Merge branch 'mt/pkt-line-comment-tweak'
|\
| * ce5f07983d18 pkt-line.h: move comment closer to the associated code
* | acdb1e1053c5 Merge branch 'mt/checkout-count-fix'
|\ \
| * | 611c7785e8e2 checkout: fix two bugs on the final count of updated entries
| * | 11d14dee4379 checkout: show bug about failed entries being included in final report
| * | ed602c3f448c checkout: document bug where delayed checkout counts entries twice
* | | f0f9a033ed3c Merge branch 'cl/rerere-train-with-no-sign'
|\ \ \
| * | | cc391fc88663 contrib/rerere-train: avoid useless gpg sign in training
| o | | bbea4dcf42b2 Git 2.37.1
| / /
o / / 3d8e3dc4fc22 Merge branch 'ds/rebase-update-ref' <--- Merge Base
/ /
o / e4a4b31577c7 Git 2.37
/
o 359da658ae32 Git 2.35.4

These simple examples are only a start to the kind of information Git uses from a repository’s commit history. We will discuss some of the important ways the structure of commits can be used to accelerate these queries.

The commit graph

Git stores snapshots of the repository as commits and each commit stores the following information:

  • The object ID for the tree representing the root of the worktree at this point in time.
  • The object IDs for any number of parent commits representing the previous points in time leading to this commit. We use different names for commits based on their parent count:
  • Zero parents: these commits are the starting point for the history and are called root commits.
  • One parent: these are typical commits that modify the repository with respect to the single parent. These commits are frequently referred to as patches, since their differences can be communicated in patch format using git format-patch.
  • Two parents: these commits are called merges because they combine two independent commits into a common history.
  • Three or more parents: these commits are called _octopus merges_since they combine an arbitrary number of independent commits.
  • Name and email information for the author and committer, which can be different.
  • Time information for the author time and committer time, which can be different.
  • A commit message, which represents additional metadata. This information is mostly intended for human consumption, so you should write it carefully. Some carefully-formatted trailer lines in the message can be useful for automation. One such trailer is the Co-authored-by: trailer which allows having multiple authors of a single commit.

The commit graph is the directed graph whose vertices are the commits in the repository and where a commit has a directed edge to each of its parents. With this representation in mind, we can visualize the commit history as dots and arrows.
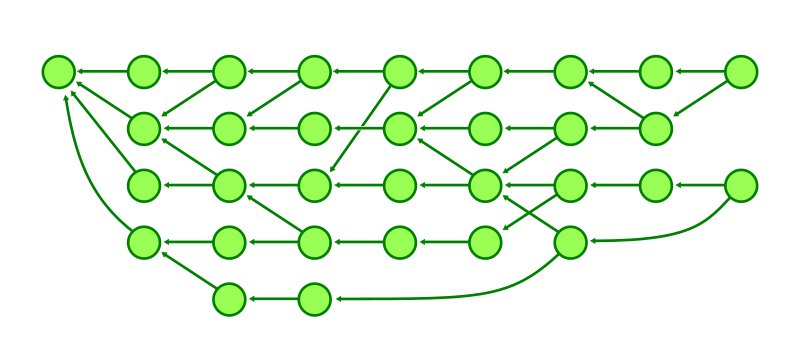
Visualization of the git commit graph using dots and arrows.

Graph databases need not apply

There are a number of graph databases that store general-purpose graph relationships. While it would be possible to store commits, trees, and blobs in such a database, those databases are instead designed for queries of limited-depth. They expect to walk only a few relationships, and maybe there are many relationships from a single node.

When considering general-purpose graph databases, think about social networks. Think about the concept of six degrees of separation and how almost every node is reachable within a short distance. In these graphs, the number of relationships at a given node can vary wildly. Further, the relationships are mainly unordered.

Git is not like that. It is rare to refer to a commit directly by its object ID. Instead Git commands focus on the current set of references. The references are much smaller in number than the total number of commits, and we might need to walk thousands of commit-parent edges before satisfying even the simplest queries.

Git also cares about the order of the parent relationships. When a merge commit is created, the parents are ordered. The first parent has a special role here. The convention is that the first parent is the previous value of the branch being updated by the merge operation. If you use pull requests to update a branch, then you can use git log --first-parent to show the list of merge commits created by that pull request.

$ git log --oneline --first-parent
2d79a03 Merge pull request #797 from ldennington/ssl-cert-updates
e209b3d Merge pull request #790 from cornejom/gitlab-support-docs
b83bf02 Merge pull request #788 from ldennington/arm-fix
cf5a693 (tag: v2.0.785) Merge pull request #778 from GyroJoe/main
dd4fe47 Merge pull request #764 from timsu92/patch-1
428b40a Merge pull request #759 from GitCredentialManager/readme-update
0d6f1c8 (tag: v2.0.779) Merge pull request #754 from mjcheetham/bb-newui
a9d78c1 Merge pull request #756 from mjcheetham/win-manifest

Git’s query pattern is so different from general-purpose graph databases that we need to use specialized storage and algorithms suited to its use case.

Git’s commit-graph file

All of Git’s functionality can be done by loading each commit’s contents out of the object store, parsing its header to discover its parents, and then repeating that process for each commit we need to examine. This is fast enough for small repositories, but as the repository increases in size the overhead of parsing these plain-text files to get the graph relationships becomes too expensive. Even the fact that we need a binary search to locate the object within the packfile begins to add up.

Git’s solution is the commit-graph file. You can create one in your own repository using git commit-graph write --reachable, but likely you already get one through git gc --auto or through background maintenance.

The file acts as a query index by storing a structured version of the commit graph data, such as the parent relationships as well as the commit date and root tree information. This information is sufficient to satisfy the most expensive parts of most history queries. This avoids the expensive lookup and parsing of the commit messages from the object store except when a commit needs to be output to the user.

We can think about the commit-graph as a pair of database tables. The first table stores each commit with its object ID, root tree, date, and first two parents as the columns. A special value, -1, is used to indicate that there is no parent in that position, which is important for root commits and patches.

The vast majority of commits have at most two parents, so these two columns are sufficient. However, Git allows an arbitrary number of parents, forming octopus merges. If a commit has three or more parents, then the second parent column has a special bit indicating that it stores a row position in a second table of overflow edges. The remaining parents form a list starting at that row of the overflow edges table, each position stores the integer position of a parent. The list terminates with a parent listed along with a special bit.

In the figure below, the commit at row 0 has a single parent that exists at row 2. The commit at row 4 is a merge whose second parent is at row 5. The commit at row 8 is an octopus merge with first parent at row 3 and the remaining parents come from the parents table: 2, 5, and 1.
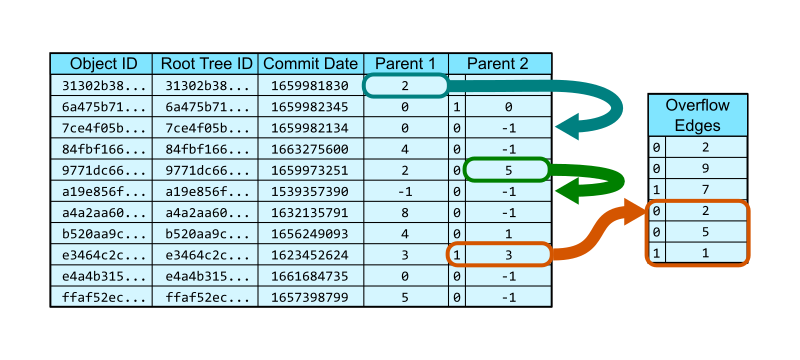
Vsiualization of the commit-graph as a database table.

One important thing about the commit-graph file is that it is closed under reachability. That means that if a commit is in the file, then so is its parent. This means that a commit’s parents can be stored as row numbers instead of as full object IDs. This provides a constant-time lookup when traversing between a commit and its parent. It also compresses the commit-graph file since it only needs four bytes per parent.

The structure of the commit-graph file speeds up commit history walks significantly, without any changes to the commit walk algorithms themselves. This is mainly due to the time it takes to visit a commit. Without the commit-graph file, we follow this pattern:

  1. Start with an Object ID.
  2. Do a lookup in the object store to see where that object is stored.
  3. Load the object content from the loose object or pack, decompressing the data from disk.
  4. Parse that object file looking for the parent object IDs.

This loop is visualized below.
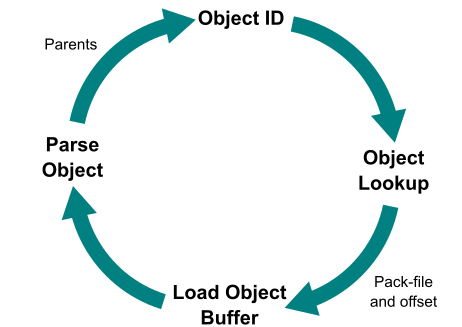
Visualization of the loop pattern used to visit a commit without the commit-graph.

When a commit-graph file exists, we have a way to eject out of this loop and into a much tighter loop. We add an extra step before doing a generic object lookup in the object store: use a binary search to find that object ID in the commit-graph file. This operation is logarithmic in the number of commits, not in the total number of objects in the repository. If the commit-graph does not have that commit, then continue in the old loop. Check the commit-graph each time so we can eventually find a commit and its position in the commit-graph file.

Once we have a commit in the commit-graph file, we can navigate immediately to the row that stores that commit’s information, then load the parent commits by their position. This means that we can lookup the parents in constant time without doing any binary search! This loop is visualized below.
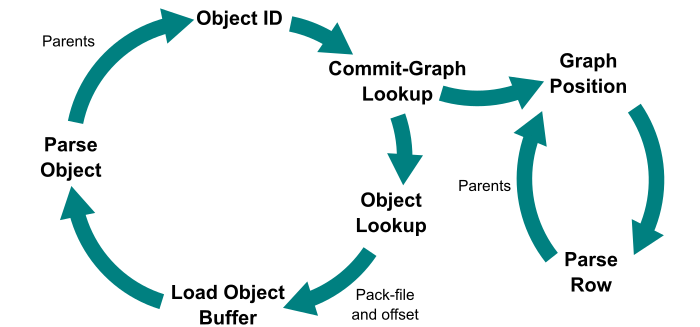
Visualization of the loop that looks up parents in constant time without doing any binary search.

This reduced data footprint makes it clear that we can speed up certain queries on the basis of parsing speed alone. The git rev-list command is great for showing this because it prints the object IDs of the commits and not the commit messages. Thus, we can test how long it takes to walk the full commit graph with and without the commit-graph file.

The Linux kernel repository is an excellent candidate for testing these queries, since it is publicly available and has over a million commits. You can replicate these tests by writing a commit-graph file and toggling the core.commitGraph config setting.

Command Without
commit-graph
With
commit-graph
git rev-list v5.19 6.94s 0.98s
git rev-list v5.0..v5.19 2.51s 0.30s
git merge-base v5.0 v5.19 2.59s 0.24s

Avoiding the expensive commit parsing results in a nice constant factor speedup (about 6x in these examples), but we need something more to get even better performance out of certain queries.

Reachability indexes

One of the most important questions we ask about commits is “can commit A reach commit B?” If we can answer that question quickly, then commands such as git tag --contains and git branch --contains become very fast.

Providing a positive answer can be very difficult, and most times we actually want to traverse the full path from A to B, so there is not too much value in that answer. However, we can learn a lot from the opposite answer when we can be sure that A cannot reach B.

The commit-graph file provides a location for adding new information to our commits that do not exist in the commit object format by default. The new information that we store is called a generation number. There are multiple ways to compute a generation number, but the most important property we need to guarantee is the following:

If the generation number of a commit A is less than the generation number of a commit B, then A cannot reach B.

In this way, generation numbers form a negative reachability index in that they can help us determine that some commits definitely cannot reach some other set of commits.

The simplest generation number is called topological level and it is defined this way:

  1. If a commit has no parents, then its topological level is 1.
  2. Otherwise, the topological level of a commit is one more than the maximum of the topological level of its parents.

Our earlier commit graph figure was already organized by topological level, but here it is shown with those levels marked by dashed lines.
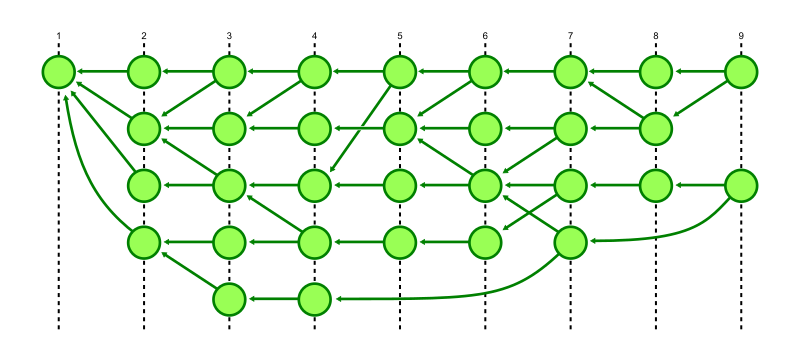
Visualization of the commit graph with topological levels marked by dashed lines.

The topological level satisfies the property of a generation number because every commit has topological level strictly larger than its parents, which implies that everything that commit can reach has strictly smaller topological level. Conversely, if something has larger topological level, then it is not reachable from that commit.

You may have noticed that I did not mention what is implied when two commits have the same generation number. While we could surmise that equal topological level implies that neither commit can reach the other, it is helpful to leave equality as an unknown state. This is because commits that are in the repository but have not yet been added to the commit-graph file do not have a precomputed generation number. Internally, Git treats these commits as having generation number infinity which is larger than all of the precomputed generation numbers in the commit-graph. However, Git can do nothing when two commits with generation number infinity are compared. Instead of special-casing these commits, Git does not assume anything about equal generation number.

Stopping walks short with generation numbers

Let’s explore how we can use generation numbers to speed up commit history queries. The first category to explore are reachability queries, such as:

  • git tag --contains <b> returns the list of tags that can reach the commit <b>.
  • git merge-base --is-ancestor <b> <a> returns an exit code of 0 if and only if <b> is an ancestor of <a> (<b> is reachable from <a>)

Both of these queries seek to find paths to a given point <b>. The natural algorithm is to start walking and report success if we ever discover the commit <b>. However, this might lead to walking every single commit before determining that we cannot in fact reach <b>. Before generation numbers, the best approach was to use a breadth-first search using commit date as a heuristic for walking the most recent commits first. This minimized the number of commits to walk in the case that we did eventually find <b>, but does not help at all if we cannot find <b>.

With generation numbers, we can gain two new enhancements to this search.

The first enhancement is that we can stop exploring a commit if its generation number is below the generation number of our target commit. Those commits of smaller generation could never contribute to a path to the target, so avoid walking them. This is particularly helpful if the target commit is very recent, since that cuts out a huge amount of commits from the search space.

In the figure below, we discover that commit A can reach commit B, but we explored every reachable commit with higher generation. We know that we do not need to explore below generation number 4.
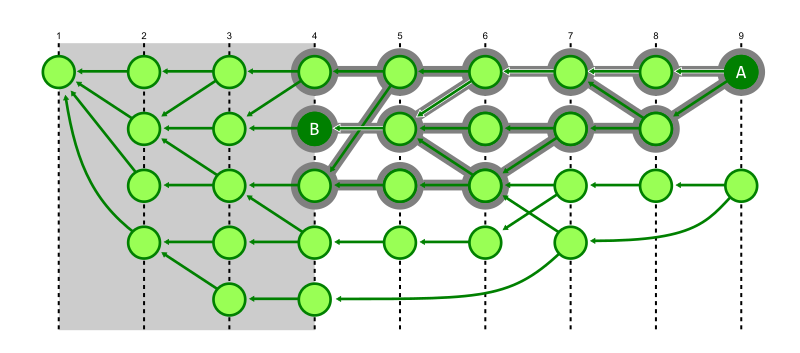
Figure showing how generation numbers can speed up commit history queries.

The second enhancement is that we can switch from breadth-first search to a depth-first search. This heuristic exploits some structure about typical repositories. The first parent of a commit is typically special, representing the previous value of the branch before the merge. The later parents are typically small topic branches merging a few new commits into the trunk of the repository. By walking the first parent history, we can navigate quickly to the generation number cutoff where the target commit is likely to be. As we backtrack from that cutoff, we are likely to find the merge commit that introduced the target commit sooner than if we had walked all recent commits first.

In the figure below, we demonstrate the same reachability query from commit A to commit B, where Git avoids walking below generation 4, but the depth-first search also prevents visiting a number of commits that were marked as visited in the previous figure.
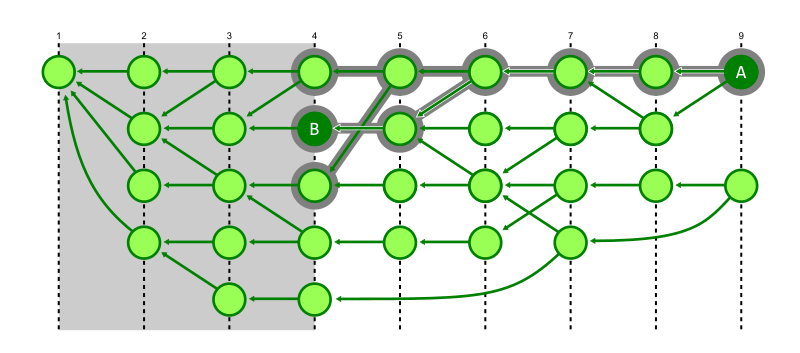
Figure showing a reachability query from commit A to commit B enhanced by depth-first search.

Note that this depth-first search approach is less efficient if we do not have the first generation number cutoff optimization, because the walk would spend most of its time exploring very old commits.

These two walks together can introduce dramatic improvements to our reachability queries.

Command Without commit-graph With commit-graph
git tag --contains v5.19~100 7.34s 0.04s
git merge-base --is-ancestor v5.0 v5.19 2.64s 0.02s

Note that since git tag --contains is checking reachability starting at every tag, it needs to walk the entire commit history even from old tags in order to be sure they cannot reach the target commit. With generation numbers, the cutoff saves Git from even starting a walk from those old tags. The git merge-base --is-ancestor command is faster even without generation numbers because it can terminate early once the target commit is found.

However, with the commit-graph file and generation numbers, both commands benefit from the depth-first search as the target commit is on the first-parent history from the starting points.

If you’re interested to read the code for this depth-first search in the Git codebase, then read the can_all_from_reach_with_flags() method which is a very general form of the walk. Take a look at how it is used by other callers such as repo_is_descendant_of() and notice how the presence of generation numbers determines which algorithm to use.

Topological sorting

Generation numbers can help other queries where it is less obvious that a reachability index would help. Specifically, git log --graph displays all reachable commits, but uses a special ordering to help the graphical visualization.

git log --graph uses a sorting algorithm called topological sort to present the commits in a pleasing order. This ordering has one hard requirement and one soft requirement.

The hard requirement is that every commit appears before its parents. This is not guaranteed by default in git log, since the default sort uses commit dates as a heuristic during the walk. Commit dates could be skewed and a commit could appear after one of its parents because of date skew.

The soft requirement is that commits are grouped together in an interesting way. When git log --graph shows a merge commit, it shows the commits “introduced” by the merge before showing the first parent. This means that the second parent is shown first followed by all of the commits it can reach that the first parent cannot reach. Typically, this will look like the commits from the topic branch that were merged in that pull request. We can see how this works with the following example from the git/git repository.

$ git log --oneline --graph -n 10 091680472db
* 091680472d Merge branch 'tb/midx-race-in-pack-objects'
|\
| * 4090511e40 builtin/pack-objects.c: ensure pack validity from MIDX bitmap objects
| * 5045759de8 builtin/pack-objects.c: ensure included `--stdin-packs` exist
| * 58a6abb7ba builtin/pack-objects.c: avoid redundant NULL check
| * 44f9fd6496 pack-bitmap.c: check preferred pack validity when opening MIDX bitmap
* | d8c8dccbaa Merge branch 'ds/object-file-unpack-loose-header-fix'
|\ \
| * | 8a50571a0e object-file: convert 'switch' back to 'if'
* | | a9e7c3a6ef Merge branch 'pb/use-freebsd-12.3-in-cirrus-ci'
|\ \ \
| * | | c58bebd4c6 ci: update Cirrus-CI image to FreeBSD 12.3
| | |/
| |/|
* | | b3b2ddced2 Merge branch 'ds/bundle-uri'
|\ \ \

$ git log --oneline --graph --date-order -n 10 091680472db
* 091680472d Merge branch 'tb/midx-race-in-pack-objects'
|\
* \ d8c8dccbaa Merge branch 'ds/object-file-unpack-loose-header-fix'
|\ \
* \ \ a9e7c3a6ef Merge branch 'pb/use-freebsd-12.3-in-cirrus-ci'
|\ \ \
* \ \ \ b3b2ddced2 Merge branch 'ds/bundle-uri'
|\ \ \ \
* \ \ \ \ 83937e9592 Merge branch 'ns/batch-fsync'
|\ \ \ \ \
* \ \ \ \ \ 377d347eb3 Merge branch 'en/sparse-cone-becomes-default'
|\ \ \ \ \ \
* | | | | | | 2668e3608e Sixth batch
* | | | | | | 4c9b052377 Merge branch 'jc/http-clear-finished-pointer'
|\ \ \ \ \ \ \
* \ \ \ \ \ \ \ db5b7c3e46 Merge branch 'js/ci-gcc-12-fixes'
|\ \ \ \ \ \ \ \
* | | | | | | | | 1bcf4f6271 Fifth batch

Notice that the first example with only --graph brought the commits introduced by the merge to the top of the order. Adding --date-order changes this ordering goal to instead present commits by their commit date, hiding those introduced commits below a long list of merge commits.

The basic algorithm for topological sorting is Kahn’s algorithm which follows two big steps:

  1. Walk all reachable commits, counting the number of times a commit appears as a parent of another commit. Call these numbers the in-degree of the commit, referencing the number of incoming edges.
  2. Walk the reachable commits, but only visit a commit if its in-degree value is zero. When visiting a commit, decrement the in-degree value of each parent.

This algorithm works because at least one of our starting points will have in-degree zero, and then decrementing the in-degree value is similar to deleting the commit from the graph, always having at least one commit with in-degree zero.

But there’s a huge problem with this algorithm! It requires walking all reachable commits before writing even one commit for the user to see. It would be much better if our algorithm would be fast to show the first page of information, so the computation could continue while the user has something to look at.

Typically, Git will show the results in a pager such as less, but we can emulate that experience using a commit count limit with the -n 100 argument. Trying this in the Linux kernel takes over seven seconds!

With generation numbers, we can perform an in-line form of Kahn’s algorithm to quickly show the first page of results. The trick is to perform both steps of the algorithm at the same time.

To perform two walks at the same time, Git creates structures that store the state of each walk. The structures are initialized with the starting commits. The in-degree walk uses a priority queue ordered by generation number and that walk starts by computing in-degrees until the maximum generation in that priority queue is below the minimum generation number of the starting positions. The output walk uses a stack, which gives us the nice grouping of commits, but commits are not added unless their in-degree value is zero.

To guarantee that the output walk can add a commit to the stack, it first checks with the status of the in-degree walk to see that the maximum generation in its queue is below the generation number of that commit. In this way, Git alternates between the two walks. It computes just enough of the in-degrees to know that certain commits have an in-degree of zero, then pauses that walk to output some commits to the user.
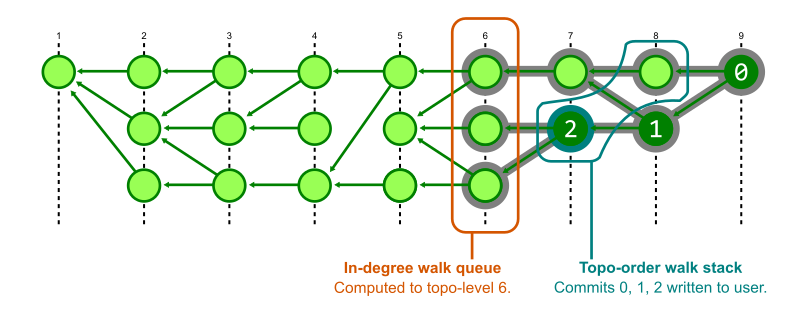
Visualization of Git structure that stores the state of each walk in order to perform two walks at the same time.

This has a significant performance improvement for our topological sorting commands.

Command Without commit-graph With commit-graph
git rev-list --topo-order -n 100 v5.19 6.88s 0.02s
git log --graph -n 100 v5.19 7.73s 0.03s
git rev-list --topo-order -n 100 v5.18..v5.19 0.39s 0.02s
git log --graph -n 100 v5.18..v5.19 0.43s 0.03s

The top two commands use an unbounded commit range, which is why the old algorithm takes so long: it needs to visit every reachable commit in the in-degree walk before writing anything to output. The new algorithm with generation numbers can explore only the recent commits.

The second two commands use a commit range (v5.18..v5.19) which focuses the search on the commits that are reachable from one commit, but not reachable from another. This actually adds a third stage to the algorithm, where first Git determines which commits are in this range. That algorithm can use a priority queue based on commit date to discover that range without walking the entire commit history, so the old algorithm speeds up for these cases. The in-degree walk still needs to walk that entire range, so it is still slower than the new algorithm as long as that range is big enough.

This idea of a commit range operating on a smaller subgraph than the full commit history actually requires that our interleaved topological sort needs a third walk to determine which commits should be excluded from the output. If you want to learn more about this three-stage algorithm, then read the commit that introduced the walk to Git’s codebase for the full details.

Generation number v2: corrected commit dates

The earlier definition of a generation number was intentionally generic. This is because there are actually multiple possible generation numbers even in the Git codebase!

The definition of topological level essentially uses the smallest possible integer that could be used to satisfy the property of a generation number. The simplicity is nice for understanding, but it has a drawback. It is possible to make the algorithms using generation number worse if you create your commit history in certain ways.

Most of the time, merge commits introduce a short list of recent commits into the commit history. However, some times those merges introduce a commit that’s based on a very old commit. This can happen when fixing a bug in a really old area of code and the developer wants to apply the fix as early as possible so it can merge into old maintenance branches. However, this means that the topological level is much smaller for that commit than for other commits created at similar times.

In this sense, the commit date is a much better heuristic for limiting the commit walk. The only problem is that we can’t trust it as an accurate generation number! Here is where a solution was found: a new generation number based on commit dates. This was implemented as part of a Google Summer of Code project in 2020.

The corrected commit date is defined as follows:

  • If a commit has no parents, then its corrected commit date is the same as its commit date.
  • Otherwise, determine the maximum corrected commit date of the commit’s parents. If that maximum is larger than the commit date, then add one to that maximum. Otherwise, use the commit date.

Using corrected commit date leads to a wider variety of values in the generation number of each commit in the commit graph. The figure below is the same graph as in the earlier examples, but the commits have been shifted as they could be using corrected commit dates on the horizontal axis.
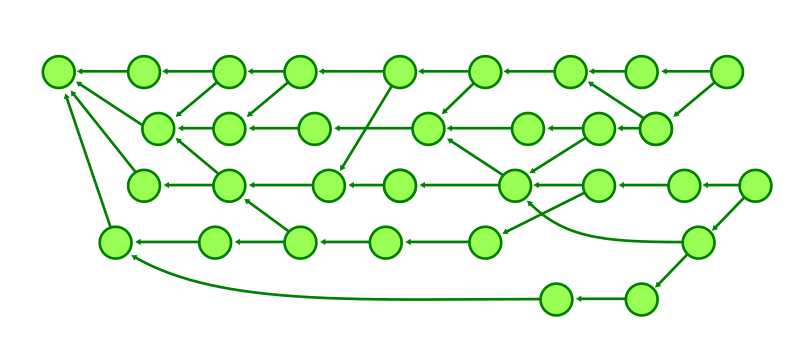
Visualization of the commit graph with commits shifted as they could be using corrected commit dates on the horizontal axis.

This definition flips the generation number around. If possible, use the commit date. If not, use the smallest possible value that satisfies the generation number properties with respect to the corrected commit dates of the commit’s parents.

In performance testing, corrected commit dates solve these performance issues due to recent commits based on old commits. In addition, some Git commands generally have slight improvements over topological levels.

For example, the search from A to C in the figure below shows how many commits must be visited to determine that A cannot reach C when using topological level.

Visualization of a commit graph search showing how many commits must be visited to determine that A cannot reach C when using topological level.

However, switching to using corrected commit dates, the search space becomes much smaller.
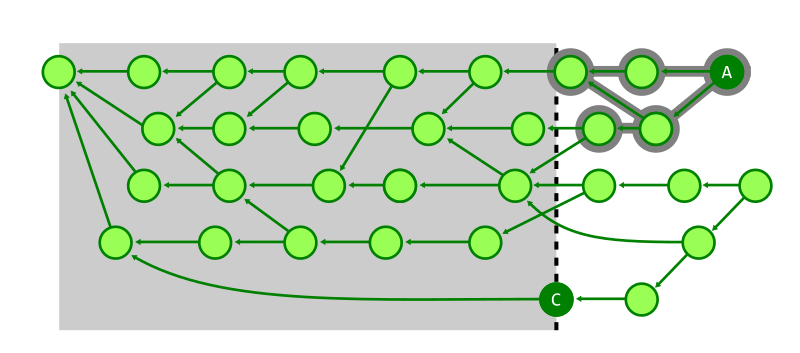
Visualization of the commit graph showing the smaller search space when using corrected commit dates.

Recent versions of Git have transitioned to corrected commit dates, but you can test against topological levels by adjusting the commitGraph.generationVersion config option.

Out of the weeds again

We’ve gone very deep into the commit-graph file and reachability algorithms. The on-disk file format is customized to Git’s needs when answering these commit history queries. Thus, it is a type of query index much like one could define in an application database. The rabbit hole goes deeper, though, with yet another level of query index specialized to other queries.

Make sure that you have a commit-graph file accelerating your Git repositories! You can ensure this happens in one of several ways:

  1. Manually run git commit-graph write --reachable.
  2. Enable the fetch.writeCommitGraph config option.
  3. Run git maintenance start and let Git write it in the background.

In the next part of this blog series, we will explore how Git file history queries use the structure of tree objects and the commit graph to limit how many objects need to be parsed. We’ll also talk about a special file history index that is stored in the commit-graph and greatly accelerates file history queries in large repositories.

I’ll also be speaking at Git Merge 2022 covering all five parts of this blog series, so I look forward to seeing you there!

AWS Week in Review – August 29, 2022

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/aws-week-in-review-august-29-2022/

I’ve just returned from data and machine learning (ML) conferences in Los Angeles and San Francisco, California. It’s been great to chat with customers and developers about the latest technology trends and use cases. This past week has also been packed with launches at AWS.

Last Week’s Launches
Here are some launches that got my attention during the previous week:

Amazon QuickSight announces fine-grained visual embedding. You can now embed individual visuals from QuickSight dashboards in applications and portals to provide key insights to users where they’re needed most. Check out Donnie’s blog post to learn more, and tune into this week’s The Official AWS Podcast episode.

Sample Web App with a Visual

Sample Web App with a Visual

Amazon SageMaker Automatic Model Tuning is now available in the Europe (Milan), Africa (Cape Town), Asia Pacific (Osaka), and Asia Pacific (Jakarta) Regions. In addition, SageMaker Automatic Model Tuning now reuses SageMaker Training instances to reduce start-up overheads by 20x. In scenarios where you have a large number of hyperparameter evaluations, the reuse of training instances can cumulatively save 2 hours for every 50 sequential evaluations.

Amazon RDS now supports setting up connectivity between your RDS database and EC2 compute instance in one click. Amazon RDS automatically sets up your VPC and related network settings during database creation to enable a secure connection between the EC2 instance and the RDS database.

In addition, Amazon RDS for Oracle now supports managed Oracle Data Guard Switchover and Automated Backups for replicas. With the Oracle Data Guard Switchover feature, you can reverse the roles between the primary database and one of its standby databases (replicas) with no data loss and a brief outage. You can also now create Automated Backups and manual DB snapshots of an RDS for Oracle replica, which reduces the time spent taking backups following a role transition.

Amazon Forecast now supports what-if analyses. Amazon Forecast is a fully managed service that uses ML algorithms to deliver highly accurate time series forecasts.  You can now use what-if analyses to quantify the potential impact of business scenarios on your demand forecasts.

AWS Asia Pacific (Jakarta) Region now supports additional AWS services and EC2 instance types – Amazon SageMaker, AWS Application Migration Service, AWS Glue, Red Hat OpenShift Service on AWS (ROSA), and Amazon EC2 X2idn and X2iedn instances are now available in the Asia Pacific (Jakarta) Region.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Here are some additional news, blog posts, and fun code competitions you may find interesting:

Scaling AI and Machine Learning Workloads with Ray on AWS – This past week, I attended Ray Summit in San Francisco, California, and had great conversations with the community. Check out this blog post to learn more about AWS contributions to the scalability and operational efficiency of Ray on AWS.

Ray on AWS

New AWS Heroes – It’s great to see both new and familiar faces joining the AWS Heroes program, a worldwide initiative that acknowledges individuals who have truly gone above and beyond to share knowledge in technical communities. Get to know them in the blog post!

DFL Bundesliga Data Shootout – DFL Deutsche Fußball Liga launched a code competition, powered by AWS: the Bundesliga Data Shootout. The task: Develop a computer vision model to classify events on the pitch. Join the competition as an individual or in a team and win prizes.

Become an AWS GameDay World Champion – AWS GameDay is an interactive, team-based learning experience designed to put your AWS skills to the test by solving real-world problems in a gamified, risk-free environment. Developers of all skill levels can get in on the action, to compete for worldwide glory, as well as a chance to claim the top prize: an all-expenses-paid trip to AWS re:Invent Las Vegas 2022!

Learn more about the AWS Impact Accelerator for Black Founders from one of the inaugural members of the program in this blog post. The AWS Impact Accelerator is a series of programs designed to help high-potential, pre-seed start-ups led by underrepresented founders succeed.

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

AWS SummitAWS Global Summits – AWS Global Summits are free events that bring the cloud computing community together to connect, collaborate, and learn about AWS.

Registration is open for the following in-person AWS Summits that might be close to you in August and September: Canberra (August 31), Ottawa (September 8), New Delhi (September 9), and Mexico City (September 21–22), Bogotá (October 4), and Singapore (October 6).

AWS Community DayAWS Community Days – AWS Community Day events are community-led conferences that deliver a peer-to-peer learning experience, providing developers with a venue for them to acquire AWS knowledge in their preferred way: from one another.

In September, the AWS community will host events in the Bay Area, California (September 9) and in Arlington, Virginia (September 30). In October, you can join Community Days in Amersfoort, Netherlands (October 3), in Warsaw, Poland (October 14), and in Dresden, Germany (October 19).

That’s all for this week. Check back next Monday for another Week in Review! And maybe I’ll see you at the AWS Community Day here in the Bay Area!

– Antje

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Git’s database internals I: packed object store

Post Syndicated from Derrick Stolee original https://github.blog/2022-08-29-gits-database-internals-i-packed-object-store/

Developers collaborate using Git. It is the medium that allows us to share code, work independently on our own machines, and then finally combine our efforts into a common understanding. For many, this is done by following some well-worn steps and sticking to that pattern. This works in the vast majority of use cases, but what happens when we need to do something new with Git? Knowing more about Git’s internals helps when exploring those new solutions.

In this five-part blog post series, we will illuminate Git’s internals to help you collaborate via Git, especially at scale.

It might also be interesting because you love data structures and algorithms. That’s what drives me to be interested in and contribute to Git.

Git’s architecture follows patterns that may be familiar to developers, except the patterns come from a different context. Almost all applications use a database to persist and query data. When building software based on an application database system, it’s easy to get started without knowing any of the internals. However, when it’s time to scale your solution, you’ll have to dive into more advanced features like indexes and query plans.

The core idea I want to convey is this:

Git is the distributed database at the core of your engineering system.

Here are some very basic concepts that Git shares with application databases:

  1. Data is persisted to disk.
  2. Queries allow users to request information based on that data.
  3. The data storage is optimized for these queries.
  4. The query algorithms are optimized to take advantage of these structures.
  5. Distributed nodes need to synchronize and agree on some common state.

While these concepts are common to all databases, Git is particularly specialized. Git was built to store plain-text source code files, where most change are small enough to read in a single sitting, even if the codebase contains millions of lines. People use Git to store many other kinds of data, such as documentation, web pages, or configuration files.

While many application databases use long-running processes with significant amounts of in-memory caching, Git uses short-lived processes and uses the filesystem to persist data between executions. Git’s data types are more restrictive than a typical application database. These aspects lead to very specialized data storage and access patterns.

Today, let’s dig into the basics of what data Git stores and how it accesses that data. Specifically, we will learn about Git’s object store and how it uses packfiles to compress data that would otherwise contain redundant information.

Git’s object store

The most fundamental concepts in Git are Git objects. These are the “atoms” of your Git repository. They combine in interesting ways to create the larger structure. Let’s start with a quick overview of the important Git objects. Feel free to skip ahead if you know this, or you can dig deep into Git’s object model if you’re interested.

In your local Git repositories, your data is stored in the .git directory. Inside, there is a .git/objects directory that contains your Git objects.

$ ls .git/objects/
01  34  9a  df  info    pack

$ ls .git/objects/01/
12010547a8990673acf08117134bdc181bd735

$ ls .git/objects/pack/
multi-pack-index
pack-7017e6ce443801478cf19006fc5499ba1c4d2960.idx
pack-7017e6ce443801478cf19006fc5499ba1c4d2960.pack
pack-9f9258a8ffe4187f08a93bcba47784e07985d999.idx
pack-9f9258a8ffe4187f08a93bcba47784e07985d999.pack

The .git/objects directory is called the object store. It is a content-addressable data store, meaning that we can retrieve the contents of an object by providing a hash of those contents.

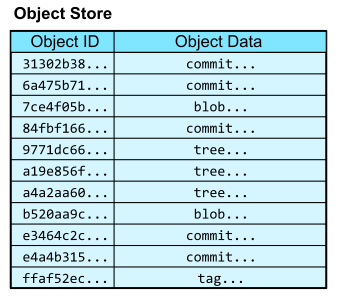
In this way, the object store is like a database table with two columns: the object ID and the object content. The object ID is the hash of the object content and acts like a primary key.

Table with columns labeled Object ID and Object Data

Upon first encountering content-addressable data stores, it is natural to ask, “How can we access an object by hash if we don’t already know its content?” We first need to have some starting points to navigate into the object store, and from there we can follow links between objects that exist in the structure of the object data.

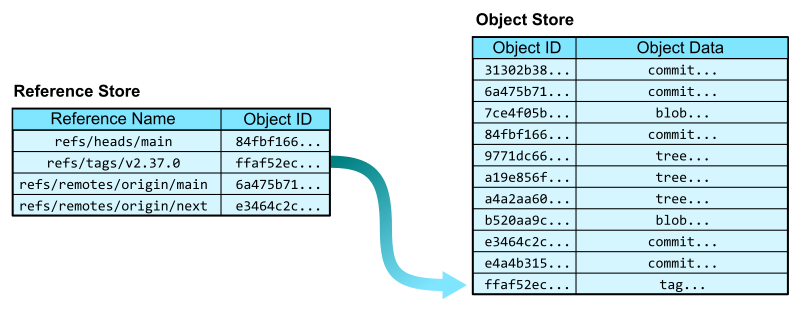
First, Git has references that allow you to create named pointers to keys in the object database. The reference store mainly exists in the .git/refs/ directory and has its own advanced way of storing and querying references efficiently. For now, think of the reference store as a two-column table with columns for the reference name and the object ID. In the reference store, the reference name is the primary key.

Image showing how the Object ID table relates to the Object Store

Now that we have a reference store, we can navigate into the object store from some human-readable names. In addition to specifying a reference by its full name, such as refs/tags/v2.37.0, we can sometimes use short names, such as v2.37.0 where appropriate.

In the Git codebase, we can start from the v2.37.0 reference and follow the links to each kind of Git object.

  • The refs/tags/v2.37.0 reference points to an annotated tag object. An annotated tag contains a reference to another object (by object ID) and a plain-text message.
  • That tag’s object references a commit object. A commit is a snapshot of the worktree at a point in time, along with connections to previous versions. It contains links to parent commits, a root tree, as well as metadata, such as commit time and commit message.
  • That commit’s root tree references a tree object. A tree is similar to a directory in that it contains entries that link a path name to an object ID.
  • From that tree, we can follow the entry for README.md to find a blob object. Blobs store file contents. They get their name from the tree that points to them.

Image displaying hops through the object database in response to a user request.

From this example, we navigated from a ref to the contents of the README.md file at that position in the history. This very simple request of “give me the README at this tag” required several hops through the object database, linking an object ID to that object’s contents.

These hops are critical to many interesting Git algorithms. We will explore how the graph structure of the object store is used by Git’s algorithms in parts two through four. For now, let’s focus on the critical operation of linking an object ID to the object contents.

Object store queries

To store and access information in an application database, developers interact with the database using a query language such as SQL. Git has its own type of query language: the command-line interface. Git commands are how we interact with the Git object store. Since Git has its own structure, we do not get the full flexibility of a relational database. However, there are some parallels.

To select object contents by object ID, the git cat-file command will do the object lookup and provide the necessary information. We’ve already been using git cat-file -p to present “pretty” versions of the Git object data by object ID. The raw content is not always fit for human readers, with object IDs stored as raw hashes and not hexadecimal digits, among other things like null bytes. We can also use git cat-file -t to show the type of an object, which is discoverable from the initial few bytes of the object data.

To insert an object into the object store, we can write directly to a blob using git hash-object. This command takes file content and writes it into a blob in the object store. After the input is complete, Git reports the object ID of the written blob.

$ git hash-object -w --stdin
Hello, world!
af5626b4a114abcb82d63db7c8082c3c4756e51b

$ git cat-file -t af5626b4a114abcb82d63db7c8082c3c4756e51b
blob

$ git cat-file -p af5626b4a114abcb82d63db7c8082c3c4756e51b
Hello, world!

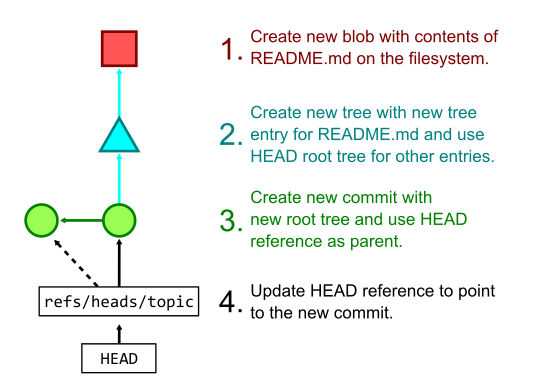
More commonly, we not only add a file’s contents to the object store, but also prepare to create new commit and tree objects to reference that new content. The git add command hashes new changes in the worktree and stores their blobs in the object store then writes the list of objects to a staging area known as the Git index. The git commit command takes those staged changes and creates trees pointing to all of the new blobs, then creates a new commit object pointing to the new root tree. Finally, git commit also updates the current branch to point to the new commit.

The figure below shows the process of creating several Git objects and finally updating a reference that happens when running git commit -a -m "Update README.md" when the only local edit is a change to the README.md file.

Image showing the process of creating several Git objects and updating references

We can do slightly more complicated queries based on object data. Using git log --pretty=format:<format-string>, we can make custom queries into the commits by pulling out “columns” such as the object ID and message, and even the committer and author names, emails, and dates. See the git log documentation for a full column list.

There are also some prebuilt formats ready for immediate use. For example, we can get a simple summary of a commit using git log --pretty=reference -1 <ref>. This query parses the commit at <ref> and provides the following information:

  • An abbreviated object ID.
  • The first sentence of the commit message.
  • The commit date in short form.
$ git log --pretty=reference -1 378b51993aa022c432b23b7f1bafd921b7c43835
378b51993aa0 (gc: simplify --cruft description, 2022-06-19)

Now that we’ve explored some of the queries we can make in Git, let’s dig into the actual storage of this data.

Compressed object storage: packfiles

Looking into the .git/objects directory again, we might see several directories with two-digit names. These directories then contain files with long hexadecimal names. These files are called loose objects, and the filename corresponds to the object ID of an object: the first two hexadecimal characters form the directory name while the rest form the filename. While the files themselves are compressed, there is not much interesting about querying these files, since Git relies on filesystem queries to satisfy most of these needs.

However, it does not take many objects before it is infeasible to store an entire Git repository using only loose objects. Not only does it strain the filesystem to have so many files, it is also inefficient when storing many versions of the same text file. Thus, Git’s packed object store in the .git/objects/pack/ directory forms a more efficient way to store Git objects.

Packfiles and pack-indexes

Each *.pack file in .git/objects/pack/ is called a packfile. Packfiles store multiple objects in compressed forms. Not only is each object compressed individually, they can also be compressed against each other to take advantage of common data.

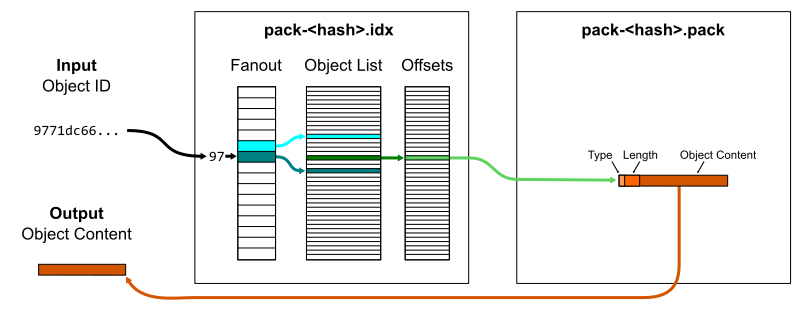
At its simplest, a packfile contains a concatenated list of objects. It only stores the object data, not the object ID. It is possible to read a packfile to find objects by object ID, but it requires decompressing and hashing each object to compare it to the input hash. Instead, each packfile is paired with a pack-index file ending with .idx. The pack-index file stores the list of object IDs in lexicographical order so a quick binary search is sufficient to discover if an object ID is in the packfile, then an offset value points to where the object’s data begins within the packfile. The pack-index operates like a query index that speeds up read queries that rely on the primary key (object ID).

One small optimization is that a fanout table of 256 entries provides boundaries within the full list of object IDs based on their first byte. This reduces the time spent by the binary search, specifically by focusing the search on a smaller number of memory pages. This works particularly well because object IDs are uniformly distributed so the fanout ranges are well-balanced.

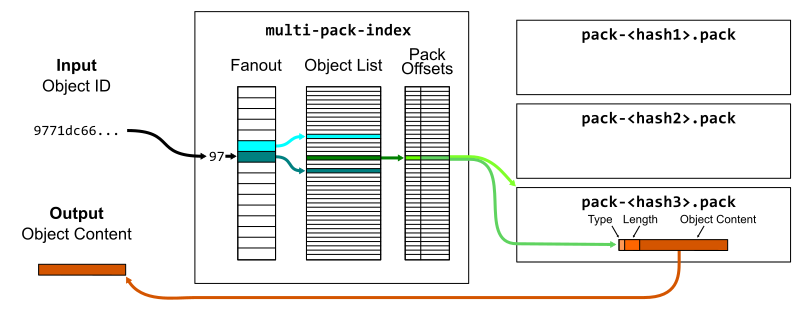
If we have a number of packfiles, then we could ask each pack-index in sequence to look up the object. A further enhancement to packfiles is to put several pack-indexes together in a single multi-pack-index, which stores the same offset data plus which packfile the object is in.

Lookups and prefixes work the same as in pack-indexes, except now we can skip the linear issue with many packs. You can read more about the multi-pack-index file and how it helps scale monorepo maintenance at GitHub.

Diffable object content

Packfiles also have a hyper-specialized version of row compression called deltification. Since read queries are only indexed by the object ID, we can perform extra compression on the object data part.

Git was built to store source code, which consists of plain-text files that are used as input to a compiler or interpreter to create applications. Git was also built to store many versions of this source code as it is changed by humans. This provides additional context about the kind of data typically stored in Git: diffable files with significant portions in common. If you’ve ever wondered why you shouldn’t store large binary files in Git repositories, this is the reason.

The field of software engineering has made it clear that it is difficult to understand applications in their entirety. Humans can grasp a very high-level view of an architecture and can parse small sections of code, but we cannot store enough information in our brains to grasp huge amounts of concrete code at once. You can read more about this in the excellent book, The Programmer’s Brain by Dr. Felienne Hermans.

Because of the limited size of our working memory, it is best to change code in small, well-documented iterations. This helps the code author, any code reviewers, and future developers looking at the code history. Between iterations, a significant majority of the code remains fixed while only small portions change. This allows Git to use difference algorithms to identify small diffs between the content of blob objects.

There are many ways to compute a difference between two blobs. Git has several difference algorithms implemented which can have drastically different results. Instead of focusing on unstructured differences, I want to focus on differences between structured object data. Specifically, tree objects usually change in small ways that are easy to compress.

Tree diffs

Git’s tree objects can also be compared using a difference algorithm that is aware of the structure of tree entries. Each tree entry stores a mode (think Unix file permissions), an object type, a name, and an object ID. Object IDs are for all intents and purposes random, but most edits will change a file without changing its mode, type, or name. Further, large trees are likely to have only a few entries change at a time.

For example, the tip commit at any major Git release only changes one file: the GIT-VERSION-GEN file. This means also that the root tree only has one entry different from the previous root tree:

$ git diff v2.37.0~1 v2.37.0
diff --git a/GIT-VERSION-GEN b/GIT-VERSION-GEN
index 120af376c1..b210b306b7 100755
--- a/GIT-VERSION-GEN
+++ b/GIT-VERSION-GEN
@@ -1,7 +1,7 @@
 #!/bin/sh

 GVF=GIT-VERSION-FILE
-DEF_VER=v2.37.0-rc2
+DEF_VER=v2.37.0

 LF='
 '

$ git cat-file -p v2.37.0~1^{tree} >old
$ git cat-file -p v2.37.0^{tree} >new

$ diff old new
13c13
< 100755 blob 120af376c147799e6c0069bac1f61709a0286cd6  GIT-VERSION-GEN
---
> 100755 blob b210b306b7554f28dc687d1c503517d2a5f87082  GIT-VERSION-GEN

Once we have an algorithm that can compute diffs for Git objects, the packfile format can take advantage of that.

Delta compression

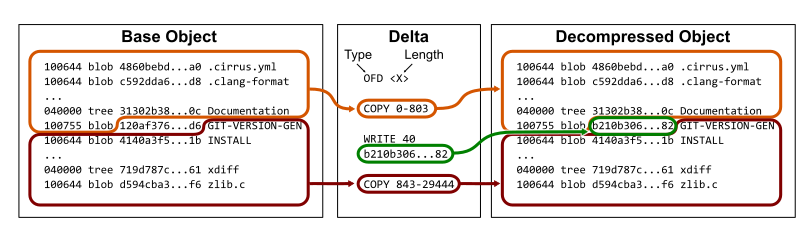
The packfile format begins with some simple header information, but then it contains Git object data concatenated together. Each object’s data starts with a type and a length. The type could be the object type, in which case the content in the packfile is the full object content (subject to DEFLATE compression). The object’s type could instead be an offset delta, in which case the data is based on the content of a previous object in the packfile.

An offset delta begins with an integer offset value pointing to the relative position of a previous object in the packfile. The remaining data specifies a list of instructions which either instruct how to copy data from the base object or to write new data chunks.

Thinking back to our example of the root tree for Git’s v2.37.0 tag, we can store that tree as an offset delta to the previous root tree by copying the tree up until the object ID 120af37..., then write the new object ID b210b30..., and finally copy the rest of the previous root tree.

Keep in mind that these instructions are also DEFLATE compressed, so the new data chunks can also be compressed similarly to the base object. For the example above, we can see that the root tree for v2.37.0 is around 19KB uncompressed, 14KB compressed, but can be represented as an offset delta in only 50 bytes.

$ git rev-parse v2.37.0^{tree}
a4a2aa60ab45e767b52a26fc80a0a576aef2a010

$ git cat-file -s v2.37.0^{tree}
19388

$ ls -al .git/objects/a4/a2aa60ab45e767b52a26fc80a0a576aef2a010
-r--r--r--   1 ... ... 13966 Aug  1 13:24 a2aa60ab45e767b52a26fc80a0a576aef2a010

$ git rev-parse v2.37.0^{tree} | git cat-file --batch-check="%(objectsize:disk)"
50

Also, an offset delta can be based on another object that is also an offset delta. This creates a delta chain that requires computing the object data for each object in the list. In fact, we need to traverse the delta links in order to even determine the object type.

For this reason, there is a cost to storing objects efficiently this way. At read time, we need to do a bit extra work to materialize the raw object content Git needs to parse to satisfy its queries. There are multiple ways that Git tries to optimize this trade-off.

One way Git minimizes the extra work when parsing delta chains is by keeping the delta-chains short. The pack.depth config value specifies an upper limit on how long delta chains can be while creating a packfile. The default limit is 50.

When writing a packfile, Git attempts to use a recent object as the base and order the delta chain in reverse-chronological order. This allows the queries that involve recent objects to have minimum overhead, while the queries that involve older objects have slightly more overhead.

However, while thinking about the overhead of computing object contents from a delta chain, it is important to think about what kind of resources are being used. For example, to compute the diff between v2.37.0 and its parent, we need to load both root trees. If these root trees are in the same delta chain, then that chain’s data on disk is smaller than if they were stored in raw form. Since the packfile also places delta chains in adjacent locations in the packfile, the cost of reading the base object and its delta from disk is almost identical to reading just the base object. The extra overhead of some CPU during the parse is very small compared to the disk read. In this way, reading multiple objects in the same delta chain is faster than reading multiple objects across different chains.

In addition, some Git commands query the object store in such a way that we are very likely to parse multiple objects in the same delta chain. We will cover this more in part III when discussing file history queries.

In addition to persisting data efficiently to disk, the packfile format is also critical to how Git synchronizes Git object data across distributed copies of the repository during git fetch and git push. We will learn more about this in part IV when discussing distributed synchronization.

Packfile maintenance

In order to take advantage of packfiles and their compressed representation of Git objects, Git needs to actually write these packfiles. It is too expensive to create a packfile for every object write, so Git batches the packfile write into certain commands.

You could roll your own packfile using git pack-objects and create a pack-index for it using git index-pack. However, you instead might want to recompute a new packfile containing your entire object store using git repack -a or git gc.

As your repository grows, it becomes more difficult to replace your entire object store with a new packfile. For starters, you need enough space to store two copies of your Git object data. In addition, the computation effort to find good delta compression is very expensive and demanding. An optimal way to do delta compression takes quadratic time over the number objects, which is quickly infeasible. Git uses several heuristics to help with this, but still the cost of repacking everything all at once can be more than we are willing to spend, especially if we are just a client repository and not responsible for serving our Git data to multiple users.

There are two primary ways to update your object store for efficient reads without rewriting the entire object store into a new packfile. One is the geometric repacking option where you can run git repack --geometric to repack only a portion of packfiles until the resulting packfiles form a geometric sequence. That is, each packfile is some fixed multiple smaller than the next largest one. This uses the multi-pack-index to keep logarithmic performance for object lookups, but will occasionally tip over to repack all of the object data. That “tip over” moment only happens when the repository doubles in size, which does not happen very often.

Another approach to reducing the amount of work spent repacking is the incremental repack task in the git maintenance command. This task collects packfiles below a fixed size threshold and groups them together, at least until their total size is above that threshold. The default threshold is two gigabytes. This task is used by default when you enable background maintenance with the git maintenance start command. This also uses the multi-pack-index to keep fast lookups, but also will not rewrite the entire object store for large repositories since once a packfile is larger than the threshold it is not considered for repacking. The storage is slightly inefficient here, since objects in newer packfiles could be stored as deltas to objects in those fixed packs, but the simplicity in avoiding expensive repository maintenance is worth that slight overhead.

If you’re interested in keeping your repositories well maintained, then think about these options. You can always perform a full repack that recomputes all delta chains using git repack -adf at any time you are willing to spend that upfront maintenance cost.

What could Git learn from other databases?

Now that we have some understanding about how Git stores and accesses packed object data, let’s think about features that exist in application database systems that might be helpful here.

One thing to note is that there are no B-trees to be found! Almost every database introduction talks about how B-trees are used to efficiently index data in a database table. Why are they not present here in Git?

The main reason Git does not use B-trees is because it doesn’t do “live updating” of packfiles and pack-indexes. Once a packfile is written, it is static until it is replaced by another packfile containing its objects. That packfile is also not accessed by Git processes until its pack-index is completely written.

In this world, objects are dynamically added to the object store by adding new loose object files (such as in git add or git commit) or by adding new packfiles (such as in git fetch). If a packfile has fixed content, then we can do the most space-and-time efficient index: a binary search tree. Specifically, performing binary search on the list of object IDs in a pack-index is very efficient. It’s not an exact binary search because there is an initial fan-out table for the first byte of the object ID. It’s kind of like a rooted binary tree, except the root node has 256 children instead of only two.

B-trees excel when data is being inserted or removed from the tree. Being able to track those modifications with minimal modifications to the overall tree structure is critical for an application database serving many concurrent requests.

Git does not currently have the capability to update a packfile in real time without shutting down concurrent reads from that file. Such a change could be possible, but it would require updating Git’s storage significantly. I think this is one area where a database expert could contribute to the Git project in really interesting ways.

Another difference between Git and most database systems is that Git runs as short-lived processes. Typically, we think of the database as a process that has data cached in memory. We send queries to the existing process and it returns results and keeps running. Instead, Git starts a new process with every “query” and relies on the filesystem for persisted state. Git also relies on the operating system to cache the disk pages during and between the processes. Expert database systems tell the kernel to stop managing disk pages and instead the database manages the page cache since it knows its usage needs better than a general purpose operating system could predict.

What if Git had a long-running daemon that could satisfy queries on-demand, but also keep that in-memory representation of data instead of needing to parse objects from disk every time? Although the current architecture of Git is not well-suited to this, I believe it is an idea worth exploring in the future.

Come back tomorrow for more!

In the next part of this blog series, we will explore how Git commit history queries use the structure of Git commits to present interesting information to the user. We’ll also explore the commit-graph file and how it acts as a specialized query index for these commands.

I’ll also be speaking at Git Merge 2022 covering all five parts of this blog series, so I look forward to seeing you there!
Open sourcing our fork of PgBouncer

Post Syndicated from Justin Kwan original https://blog.cloudflare.com/open-sourcing-our-fork-of-pgbouncer/

Open sourcing our fork of PgBouncer

Open sourcing our fork of PgBouncer

Cloudflare operates highly available Postgres production clusters across multiple data centers, supporting the transactional workloads of our core service offerings such as our DNS Resolver, Firewall, and DDoS Protection.

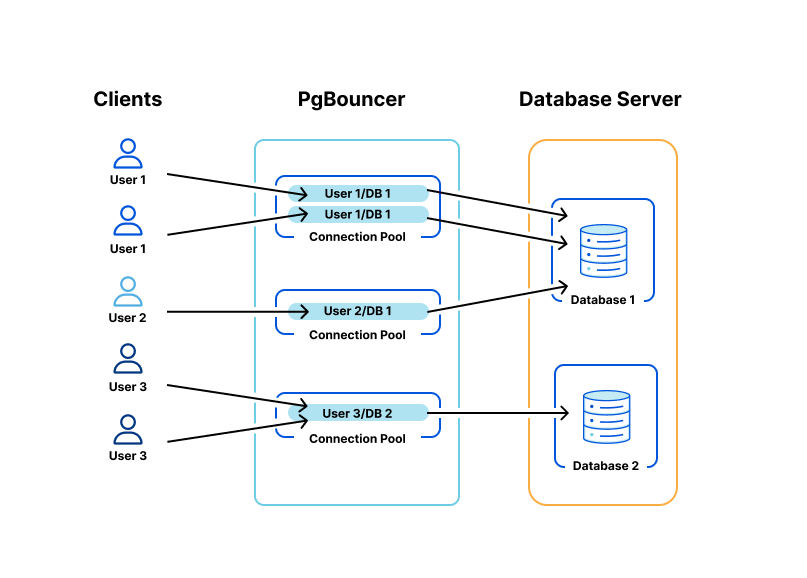
Multiple PgBouncer instances sit at the front of the gateway layer per each cluster, acting as a TCP proxy that provides Postgres connection pooling. PgBouncer’s pooling enables upstream applications to connect to Postgres, without having to constantly open and close connections (expensive) at the database level, while also reducing the number of Postgres connections used. Each tenant acquires client-side connections from PgBouncer instead of Postgres directly.

Open sourcing our fork of PgBouncer

PgBouncer will hold a pool of maximum server-side connections to Postgres, allocating those across multiple tenants to prevent Postgres connection starvation. From here, PgBouncer will forward backend queries to HAProxy, which load balances across Postgres primary and read replicas.

As an intern at Cloudflare I got to work on improving how our database clusters behave under load and open source the resulting code.

We run our Postgres infrastructure in non-containerized, bare metal environments which consequently leads to multitenant resource contention between Postgres users. To enforce stricter tenant performance isolation at the database level (CPU time utilized, memory consumption, disk IO operations), we’d like to configure and enforce connection limits per user and connection pool at PgBouncer.

To do that we had to add features and fix bugs in PgBouncer. Rather than continue to maintain a private fork we are open sourcing our code for others to use.

Authentication Rejection

The PgBouncer connection pooler offers options to enforce server connection pool size limits (effective concurrency) per user via static configuration. However, an authentication bug upstream prevented these features from correctly working when Postgres was set to use HBA authentication. Administrators who sensibly use server-side authentication could not take advantage of these user-level features.

This ongoing issue has also been experienced by others in the open-source community:

https://github.com/pgbouncer/pgbouncer/issues/484
https://github.com/pgbouncer/pgbouncer/issues/596

Root Cause

PgBouncer needs a Postgres user’s password when proxying submitted queries from client connection to a Postgres server connection. PgBouncer will fetch a user’s Postgres password defined in userlist.txt (auth_file) when a user first logs in to compare against the provided password. However, if the user is not defined in userlist.txt, Pgbouncer will fetch their password from the Postgres pg_shadow system view for comparison. This password will be used when PgBouncer subsequently forwards queries from this user to Postgres. The same applies when Postgres is configured to use HBA authentication.

Following serious debugging efforts and time spent in GDB, we found that multiple user objects are typically created for a single real user: via configuration loading from the [users] section and upon the user’s first login. In PgBouncer, any users requiring a shadow auth query would be stored under their respective database struct instance, whereas any user with a password defined in userlist.txt would be stored globally. Because the non-authenticated user already existed in memory after being parsed from the [users] section, PgBouncer assumed that the user was defined in userlist.txt, where the shadow authentication query could be skipped. It would not bother to fetch and set the user’s password upon first login, resulting in an empty user password. This is why subsequent queries submitted by the user would be rejected with authentication failure at Postgres.

To solve this, we simplified the code to globally store all users in one place rather than store different types of users (requiring different methods of authentication) in a disaggregated fashion per database or globally. Also, rather than assuming a user is authenticated if they merely exist, we keep track of whether the user requires authentication via auth query or from fetching their password from userlist.txt. This depends on how they were created.

We saw the value in troubleshooting and fixing these issues; it would unlock an entire class of features in PgBouncer for our use cases, while benefiting many in the open-source community.

New Features

We’ve also done work to implement and support additional features in PgBouncer to enforce stricter tenant performance isolation.

Previously, PgBouncer would only prevent tenants from exceeding preconfigured limits, not particularly helpful when it’s too late and a user is misbehaving or already has too many connections. PgBouncer now supports enforcing or shrinking per user connection pool limits at runtime, where it is most critically needed to throttle tenants who are issuing a burst of expensive queries, or are hogging connections from other tenants. We’ve also implemented new administrative commands to throttle the maximum connections per user or per pool at runtime.

PgBouncer also now supports statically configuring and dynamically enforcing connection limits per connection pool. This feature is extremely important in order to granularly throttle a tenant’s misbehaving connection pool without throttling and reducing availability on its other non-misbehaving pools.

PgBouncer Configuration
[users]
dns_service_user = max_user_connections=60
firewall_service_user = max_user_connections=80
[pools]
user1.database1 = pool_size=90
PgBouncer Runtime Commands
SET USER dns_service_user = ‘max_user_connections=40’;
SET POOL dns_service_user.dns_db = ‘pool_size=30’;

These new features required major refactoring around how PgBouncer stores users, databases weakly referenced and stored passwords of different users, and how we enforce killing server side connections while still in use.

Conclusion

We are committed to improving PgBouncer in open source and contributing all of our features to benefit the wider community. If you are interested, please consider contributing to our open source PgBouncer fork. After all, it is the community that makes PgBouncer possible!

Introducing Trilogy: a new database adapter for Ruby on Rails

Post Syndicated from Matthew Draper original https://github.blog/2022-08-25-introducing-trilogy-a-new-database-adapter-for-ruby-on-rails/

We’ve open sourced the database adapter we use at GitHub to connect Ruby on Rails and Active Record clients to MySQL-compatible database servers.

Trilogy is a client library for MySQL-compatible database servers, designed for performance, flexibility, and ease of embedding. We released Trilogy, with its Ruby-native wrapper, in December, and have now rounded out the set with the release of activerecord-trilogy-adapter, an Active Record adapter that allows a Ruby on Rails application to use Trilogy in place of the built-in mysql2-based adapter.

Why does Trilogy exist?

The Trilogy library is specifically designed to perform efficiently when embedded in environments like the Ruby VM, which benefits from special handling of blocking syscalls, and conscious use of dynamic memory allocation. It also aims to provide strong portability and compatibility, using a custom implementation of the network protocol to minimize dependencies needed for compilation.

After starting off on the original mysql gem, GitHub switched to mysql2 in 2011, gaining performance and reliability. But over the following years, we found it was still not quite meeting our needs. Trilogy was initially developed by Hailey Somerville and Brian Lopez to further improve GitHub’s performance and reliability, and has been backing all of our Rails monolith’s query activity since 2015. (The name is a pun: it’s the third adapter GitHub has used, and it’s used to query sequel.)

Open sourcing this adapter is the culmination of a long term effort, primarily championed first by Aaron Patterson and then by Eileen M. Uchitelle, to extract valuable database-communication behavior we’d collected and upstream it into other layers of Active Record—most recently, deferred connection verification and automatic reconnection.

Should you use Trilogy?

Compared to the mysql2 gem, Trilogy avoids a dependency on the libmariadb / libmysqlclient library, which can simplify gem installation and eliminate version mismatch issues, and minimizes the number of times data must be copied in memory when building and parsing network packets. It should simplify gem installation and be more efficient under heavy query loads.

Trilogy is thoroughly production-tested to work well for our applications, but there may be protocol features it doesn’t support (yet?) that other database configurations might require. For that reason, while we do encourage other Rails applications to try using Trilogy to interface with their MySQL-compatible database servers, it would be prudent to check things out in a staging environment first. Other than that, it should be a drop-in compatible change.

The Trilogy adapter is currently only compatible with the version of Rails that we use to run GitHub: the in-development main branch of rails/rails. After Active Record 7.1.0 is released, we will maintain a release that is compatible with the current supported release series.

Trilogy is a strong option when connecting to a MySQL-compatible database server, and we would love to hear from you if you give it a try.

Pushing Open-Source Security Forward: Insights From Black Hat 2022

Post Syndicated from Jesse Mack original https://blog.rapid7.com/2022/08/19/pushing-open-source-security-forward-insights-from-black-hat-2022/

Pushing Open-Source Security Forward: Insights From Black Hat 2022

Open-source security has been a hot topic in recent years, and it’s proven to be something of a double-edged sword. On the one hand, there’s an understanding of the potential that open-source tools hold for democratizing security, making industry best practices accessible to more organizations and helping keep everyone’s data better protected from attackers. On the other hand, open-source codebases have been the subject of some of the most serious and high-impact vulnerabilities we’ve seen over the past 12 months, namely Log4Shell and Spring4Shell.

While the feeling around open-source understandably wavers between excitement and trepidation, one thing is for sure: Open-source frameworks are here to stay, and it’s up to us to ensure they deliver on their potential and at the same time remain secure.

The future of open-source was common theme at Black Hat 2022, and two members of the Rapid7 research team — Lead Security Research Spencer McIntyre and Principal Security Researcher Curt Barnard — shined a light on the work they’ve been doing to improve and innovate with open-source tools. Here’s a look at their presentations from Black Hat, and how their efforts are helping push open-source security forward.

A more powerful Metasploit

Spencer, whose work focuses primarily on Rapid7’s widely used attacker emulation and penetration testing tool Metasploit, shared the latest and greatest improvements he and the broader team have made to the open-source framework in the past year. The upgrades they’ve made reflect a reality that security pros across the globe are feeling everyday: The perimeter is disappearing.

In a threat environment shaped by ransomware, supply chain attacks, and widespread vulnerabilities like Log4Shell, bad actors are increasingly stringing together complex attack workflows leveraging multiple vulnerabilities. These techniques allow adversaries to go from outside to within an organization’s network more quickly and easily than ever before.

The updates Spencer and team have made to Metasploit are intended to help security teams keep up with this shift, with more modern, streamlined workflows for testing the most common attack vectors. These recent improvements to Metasploit include:

Credential capturing: Credential capture is a key component of the attacker emulation toolkit, but previously, the process for this in Metasploit involved spinning up 13 different modules and managing and specifying configurations for each. Now, Metasploit offers a credential capture plugin that lets you configure all options from a single start/stop command, eliminating redundant work.

User interface (UI) optimization: URLs are commonly used to identify endpoints — particularly web applications — during attacker emulation. Until now, Metasploit required users to manually specify quite a few components when using URLs. The latest update to the Metasploit UI understands a URL’s format, so users can copy and paste them from anywhere, even right from their browser.

Payloadless session capabilities: When emulating attacks, exploits typically generate Meterpreter payloads, making them easy to spot for many antivirus and EDR solutions — and reducing their effectiveness for security testing. Metasploit now lets you run post-exploitation actions and operations without needing a payload. You can tunnel modules through SSH sessions or create a WinRM session for any Metasploit module compatible with the shell session type, removing the need for a payload like reverse shell or Meterpreter.

SMB server support: Metasploit Version 6 included SMB 3 server support, but only for client modules, which was limiting for users who were working with modern Windows targets that had disabled SMB 3 client support. Now, SMB 3 is available in all SMB server modules, so you can target modern Windows environments and have them fetch (often payload) files from Metasploit. This means you don’t need to install and configure an external service to test for certain types of vulnerabilities, including PrintNightmare.

Defaultinator: Find default credentials faster

Metasploit is at the heart of Rapid7’s commitment to open-source security, but we’re not stopping there. In addition to continually improving Metasploit, our research team works on new open-source projects that help make security more accessible for all. The latest of those is Defaultinator, a new tool that Curt Barnard announced the release of in his Black Hat Arsenal talk this year. (Curt also joined our podcast, Security Nation, to preview the announcement — check out that episode if you haven’t yet!)

Defaultinator is an open-source tool for looking up default usernames and passwords, providing an easy-to-search data repository in which security pros can query these commonly used credentials to find and eliminate them from their environment. This capability is becoming increasingly important for security teams, for a few key reasons:

  • Some commonly used pieces of hardware in IT environments come with default credentials that could give attackers an easily exploitable method of network access. Curt gave the example of the Raspberry Pi microcontroller board, which always comes with the username “pi” and password “raspberry” for initial login — a security flaw that resulted in a 10 CVSS vulnerability published in 2021.
  • Meanwhile, IoT devices have been proliferating, and many of these manufacturers don’t have security best practices at the front of their mind. That means hardcoded default credentials for first-time logins are common in this type of tool.
  • Many software engineers (Curt included) spend a lot of time in Stack Overflow, and many of the code snippets found there contain example usernames and passwords. If you aren’t careful when copying and pasting, default credentials could make their way into your production environment.

With a whopping 54 CVEs for hardcoded usernames and passwords released just in 2022 so far (by Curt’s count), security pros are in need of a fast, accurate way to audit for default credentials. But until now, the tools for these kinds of audits just haven’t been out there, let alone widely available.

That’s why it was so important to make Defaultinator, the first tool of its kind for querying default usernames and passwords, an open-source solution — to ensure broad accessibility and help as many defenders as possible. Defaultinator offers an API search-based utility or a web-based user interface if you prefer not to interact with the API. It runs in Docker, and the quickstart repository on Github takes just four lines of code to get up and running.

Watch the replays of Spencer’s and Curt’s presentations, as well as other great sessions from Black Hat 2022, at our replay page.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

OCSF: Working Together to Standardize Data

Post Syndicated from Rapid7 original https://blog.rapid7.com/2022/08/10/ocsf-working-together-to-standardize-data/

OCSF: Working Together to Standardize Data

Teams spend a lot of time normalizing data before any analysis, investigation, or response can begin. It’s an unacceptable burden for you. And its days are finally numbered.

Rapid7 and other security vendors are collaborating on an Open Cybersecurity Schema Framework (OCSF), an open standard for both data producers and users to adopt. Much like the MITRE Att@ck Framework, common language and understanding change everything.

OCSF, includes contributions from 17 leading cybersecurity and technology organizations: AWS, Cloudflare, CrowdStrike, DTEX, IBM Security, IronNet, JupiterOne, Okta, Palo Alto Networks, Rapid7, Salesforce, Securonix, Splunk, Sumo Logic, Tanium, Trend Micro, and Zscaler.

OCSF is an open standard that can be adopted in any environment, application, or solution provider and fits with existing security standards and processes. As cybersecurity solution providers incorporate OCSF standards into their products, security data normalization will become simpler, allowing teams to focus on analyzing data, identifying threats, and stopping attackers before they cause damage.

“We, as security vendors, need to do right by the security teams who work tirelessly to protect not only their organizations, but the greater community, against a constantly evolving array of threats,” said Sam Adams, Vice President of Detection and Response, Rapid7. “A step towards that is standardizing the data on which these teams rely. If we can minimize the complexity of using security data from disparate sources, we can save security professionals millions of hours every year. Rapid7 has a proud history of supporting the open-source community. We are thrilled to join our peers who share this belief and build a solution that will break down data silos, removing a heavy burden that hinders security teams’ efforts to stay ahead of threats.”

Data holds the key

The key to efficiently detecting and rapidly responding to today’s threats and attacks is data and how you use that data. It’s mission-critical for security teams to evaluate data from various sources (e.g. the endpoint, threat intelligence feeds, logs, etc.), coordinating with a myriad of security tools and solutions. In a recent study, SOC Modernization and the Role of XDR, eight in 10 organizations said they collect, process, and analyze security operations data from more than 10 sources. While it might sound like a lot, survey respondents actually want to use more data, in order to keep up with the evolving attack surface.

As the industry comes together to unburden security teams of the work required to collect and normalize data, Rapid7 will be rolling out support for OCSF, starting with InsightIDR, our joint SIEM and XDR solution. Look for updates on OCSF support in the coming months!

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

AWS Week in Review – August 8, 2022

Post Syndicated from Steve Roberts original https://aws.amazon.com/blogs/aws/aws-week-in-review-august-8-2022/

As an ex-.NET developer, and now Developer Advocate for .NET at AWS, I’m excited to bring you this week’s Week in Review post, for reasons that will quickly become apparent! There are several updates, customer stories, and events I want to bring to your attention, so let’s dive straight in!

Last Week’s launches
.NET developers, here are two new updates to be aware of—and be sure to check out the events section below for another big announcement:

Tiered pricing for AWS Lambda will interest customers running large workloads on Lambda. The tiers, based on compute duration (measured in GB-seconds), help you save on monthly costs—automatically. Find out more about the new tiers, and see some worked examples showing just how they can help reduce costs, in this AWS Compute Blog post by Heeki Park, a Principal Solutions Architect for Serverless.

Amazon Relational Database Service (RDS) released updates for several popular database engines:

  • RDS for Oracle now supports the April 2022 patch.
  • RDS for PostgreSQL now supports new minor versions. Besides the version upgrades, there are also updates for the PostgreSQL extensions pglogical, pg_hint_plan, and hll.
  • RDS for MySQL can now enforce SSL/TLS for client connections to your databases to help enhance transport layer security. You can enforce SSL/TLS by simply enabling the require_secure_transport parameter (disabled by default) via the Amazon RDS Management console, the AWS Command Line Interface (AWS CLI), AWS Tools for PowerShell, or using the API. When you enable this parameter, clients will only be able to connect if an encrypted connection can be established.

Amazon Elastic Compute Cloud (Amazon EC2) expanded availability of the latest generation storage-optimized Is4gen and Im4gn instances to the Asia Pacific (Sydney), Canada (Central), Europe (Frankfurt), and Europe (London) Regions. Built on the AWS Nitro System and powered by AWS Graviton2 processors, these instance types feature up to 30 TB of storage using the new custom-designed AWS Nitro System SSDs. They’re ideal for maximizing the storage performance of I/O intensive workloads that continuously read and write from the SSDs in a sustained manner, for example SQL/NoSQL databases, search engines, distributed file systems, and data analytics.

Lastly, there’s a new URL from AWS Support API to use when you need to access the AWS Support Center console. I recommend bookmarking the new URL, https://support.console.aws.amazon.com/, which the team built using the latest architectural standards for high availability and Region redundancy to ensure you’re always able to contact AWS Support via the console.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Here’s some other news items and customer stories that you may find interesting:

AWS Open Source News and Updates – Catch up on all the latest open-source projects, tools, and demos from the AWS community in installment #123 of the weekly open source newsletter.

In one recent AWS on Air livestream segment from AWS re:MARS, discussing the increasing scale of machine learning (ML) models, our guests mentioned billion-parameter ML models which quite intrigued me. As an ex-developer, my mental model of parameters is a handful of values, if that, supplied to methods or functions—not billions. Of course, I’ve since learned they’re not the same thing! As I continue my own ML learning journey I was particularly interested in reading this Amazon Science blog on 20B-parameter Alexa Teacher Models (AlexaTM). These large-scale multilingual language models can learn new concepts and transfer knowledge from one language or task to another with minimal human input, given only a few examples of a task in a new language.

When developing games intended to run fully in the cloud, what benefits might there be in going fully cloud-native and moving the entire process into the cloud? Find out in this customer story from Return Entertainment, who did just that to build a cloud-native gaming infrastructure in a few months, reducing time and cost with AWS services.

Upcoming events
Check your calendar and sign up for these online and in-person AWS events:

AWS Storage Day: On August 10, tune into this virtual event on twitch.tv/aws, 9:00 AM–4.30 PM PT, where we’ll be diving into building data resiliency into your organization, and how to put data to work to gain insights and realize its potential, while also optimizing your storage costs. Register for the event here.

AWS SummitAWS Global Summits: These free events bring the cloud computing community together to connect, collaborate, and learn about AWS. Registration is open for the following AWS Summits in August:

AWS .NET Enterprise Developer Days 2022 – North America: Registration for this free, 2-day, in-person event and follow-up 2-day virtual event opened this past week. The in-person event runs September 7–8, at the Palmer Events Center in Austin, Texas. The virtual event runs September 13–14. AWS .NET Enterprise Developer Days (.NET EDD) runs as a mini-conference within the DeveloperWeek Cloud conference (also in-person and virtual). Anyone registering for .NET EDD is eligible for a free pass to DeveloperWeek Cloud, and vice versa! I’m super excited to be helping organize this third .NET event from AWS, our first that has an in-person version. If you’re a .NET developer working with AWS, I encourage you to check it out!

That’s all for this week. Be sure to check back next Monday for another Week in Review roundup!

— Steve
This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Building and using Managed Components with WebCM

Post Syndicated from Yo'av Moshe original https://blog.cloudflare.com/building-using-managed-components-webcm/

Building and using Managed Components with WebCM

Building and using Managed Components with WebCM

Managed Components are here to shake up the way third-party tools integrate with websites. Two months ago we announced that we’re open sourcing parts of the most innovative technologies behind Cloudflare Zaraz, making them accessible and usable to everyone online. Since then, we’ve been working hard to make sure that the code is well documented and all pieces are fun and easy to use. In this article, I want to show you how Managed Components can be useful for you right now, if you manage a website or if you’re building third-party tools. But before we dive in, let’s talk about the past.

Third-party scripts are a threat to your website

For decades, if you wanted to add an analytics tool to your site, a chat widget, a conversion pixel or any other kind of tool – you needed to include an external script. That usually meant adding some code like this to your website:

<script src=”https://example.com/script.js”></script>

If you think about it – it’s a pretty terrible idea. Not only that you’re now asking the browser to connect to another server, fetch and execute more JavaScript code – you’re also completely giving up the control on your website. How much do you really trust this script? And how much do you trust that the script’s server wasn’t hacked, or will never get hacked in the future? In the previous blog post we showed how including one script usually results in more network calls, hogging the browser and slowing everything down. But the worst thing about these scripts is that they are completely unrestricted: JavaScript code running in the browser can hijack users, steal their credentials or credit card information, use their devices to mine cryptocurrencies, manipulate your website, leak PII, and more. Since the code in those scripts is usually minified, it’s practically impossible for you to read it and figure out what it’s doing.

Managed Components change all that. Like apps on your phone, they’re built around a permissions system. You decide if you allow a component to connect to a remote server, if you allow it to use cookies, to run code, to inject a widget to pages and more. Unlike the world of minified external scripts, it is a framework that promotes transparency. Website owners can toggle permissions on and off, and if a Managed Component wasn’t granted a permission, it will not have access to the relevant API.

But Managed Components do more than wrapping the current system with permissions – they also provide functionality that was never available before: making server-side connections, caching information, using a key-value store, manipulating responses before they are handed to the browser and more. The core of this functionality comes from the ability to execute code outside the browser. Freeing the browser from running code that was previously executed in the browser, means that your website can become approximately 40% faster. It also results in a smaller attack surface in case your tool’s vendor gets hacked.

All of this is possible thanks to the new Managed Components API. We designed it together with vendors, to make sure you can use them to write any tool, while keeping performance, security and privacy a top priority. At its core, a Managed Component is just a JavaScript module, and so every JavaScript developer should feel right at home when building one. Check out the two examples in our previous blog post to see how they actually look like, or see some Managed Components we already open sourced on GitHub.

WebCM is the open source Component Manager

When tools are loaded with a <script> tag, their code is executed by the browser. Since Managed Components don’t run in the browser, their code needs to be executed somewhere else. This is the Component Manager. We designed the APIs around Managed Components deliberately to not be tied to a specific Component Manager, and in fact, there are already two in the world: Cloudflare Zaraz, and WebCM.

WebCM, Web-based Component Manager, is our open source reference implementation of a Component Manager. If you run a website, you can use WebCM today to run Managed Components on your website, even if you’re not a Cloudflare user. If you want to create a Managed Component, you can use it like an SDK.

Over the last few months, we’ve been helping vendors to write their own Managed Components, and we will continue to do so. We open sourced WebCM to ensure that Managed Components are a technology of the Web as a whole. Everyone should be able to use WebCM to load and create Managed Components. Let’s see how to use it!

Getting started with WebCM in 5 minutes

Getting started with WebCM is easier than you think. Because WebCM works like a proxy, you can use it regardless of how your website is built. In a new folder, create a simple HTML file and call it index.html:

<!DOCTYPE html>
<html lang=”en”>
  <head>
	<meta charset="UTF-8">
	<title>My Website</title>
  </head>
  <body>
    	<h1>WebCM test website</h1>  
  </body>
</html>

Let’s serve this file by launching an HTTP serve in the same folder:

You can use Node.js:

npx http-server -p 8000

You can use Python:

python3 -m http.server

Or anything else that would serve our HTML file on http://localhost:8000/index.html.

Next, create a configuration file for WebCM. In a new directory, create a file called webcm.config.ts.

export default {
  components: [
    {
      name: 'demo',
      permissions: [
        'access_client_kv',
        'provide_server_functionality',
        'provide_widget',
        'serve_static_files',
        'client_network_requests',
      ],
    },
  ],
  target: 'http://127.0.0.1:8000',
  hostname: 'localhost',
  trackPath: '/webcm/track',
  ecommerceEventsPath: '/webcm/ecommerce',
  clientEventsPath: '/webcm/system',
  port: 8080
}

Let’s go over this configuration file:

  • components is an array that lists all the Managed Components you want to load. For now, we will load the demo component. Note that all we needed was to specify “demo”, and WebCM will go and get it from NPM for us. Other Managed Components are available on NPM too, and you can install components from other sources too. For each component, we’re defining what permissions we are giving it. You can read more about the permissions in the specifications. If we try to add the component without granting it its required permissions, WebCM will alert us.
  • target is where our origin HTTP server runs. In the previous step, we set it to run on port 8000.
  • port is the port under which WebCM will serve our website.
  • hostname is the host WebCM will bind to.
  • trackPath, clientEventsPath, ecommerceEventsPath are paths that WebCM will use to send events from the browser to its backend. We can leave these paths as they are for now, and will see how they’re used later.

! Note: Node version 17 or higher is needed for the next section

While keeping your HTTP server running, and in the same directory as webcm.config.ts, run npx webcm. Node will fetch WebCM and start it for you, and WebCM will read the configuration. First, it will fetch the required components to a components folder. When done, it will start another server that proxies your origin.

If you open http://localhost:8080/index.html in your browser now, you’d see the same page you saw at http://localhost:8000/index.html. While the pages might look similar, the one running on port 8080 has our demo Managed Component running. Moving your mouse and clicking around the page should result in messages being printed in your WebCM terminal, showing that the component was loaded and that it is receiving data. You will also notice that the page now displays a simple weather widget – this a Managed Component Widget that got appended to your page. The weather information was fetched without the browser needing to contact any additional server, and WebCM can cache that information to make sure it is served fast. Lastly, if you go to http://localhost:8080/webcm/demo/cheese, you’ll see that the component is serving a static image of a cheese. This is an example of how Managed Components can expose new endpoints on your servers, if you allow them.

The Demo Component, like its name suggests, is just a demo. We use it to showcase and test the Managed Components APIs. What if we want to add a real Managed Component to our site? Google Analytics is used by more than half of the websites on the internet, so let’s see how we edit our webcm.config.ts file to load it.

export default {
  components: [
    {
      name: 'demo',
      permissions: [
        'access_client_kv',
        'provide_server_functionality',
        'provide_widget',
        'serve_static_files',
        'client_network_requests',
      ],
    },
    {
      name: 'google-analytics',
      settings: { 'tid': 'UA-XXXXXX' },
      permissions: [
        'access_client_kv',
      ],
    },
  ],
  target: 'http://127.0.0.1:8000',
  hostname: 'localhost',
  trackPath: '/webcm/track',
  ecommerceEventsPath: '/webcm/ecommerce',
  clientEventsPath: '/webcm/system',
  port: 8080
}

In the above example, we just replaced our demo component with the Google Analytics Managed Component. Note that this component requires much fewer permissions to run – that’s because it is running 100% server-side. Remember to replace UA-XXXXXX with your real Google Universal Analytics (version 3) account identifier.

Re-running `npx webcm` will now fetch the google-analytics Managed Component and run it, with the settings you provided. If you go now to your proxied website, you won’t see anything changed. But if you go to your Google Analytics dashboard, you will start seeing page views appearing on the Real Time view. WebCM loaded the component and is sending information server-side to Google Analytics.

There are many other components you can play around with, and we’re adding more all the time. Check out the Managed Components organization on NPM or on GitHub to see the full list.

Build your own Managed Component

Managed Components isn’t a closed library of tools you can use. As mentioned before – we are gradually open sourcing more tools from our library on GitHub. If you think our components are doing something weird – please let us know with an issue, or even make a PR. Managed Components are for the benefit of everyone. Over the past few months, the Cloudflare Zaraz community on Discord and on the Cloudflare Community Forum was extremely helpful in actively reporting issues, and so we’re excited to give them the option to take one step closer to the internals behind Cloudflare Zaraz.

While improving existing Managed Components is great, the thing we’re most thrilled about is that you can now build your own Managed Components too. If you’re a third-party tool vendor – this is a way for you to create a version of your tool that is safe and performant, so customers can discover and adopt your tool easily. If you’re a website developer, you might want to tinker with Managed Components to see what kind of things you can easily move away from the browser, for performance gains.

Let’s see how easy it is to create a Managed Component that listens to every page view on our website. Run npm init managed-component in the components directory that WebCM created, and create-managed-component will take you through the process of scaffolding your component files. To start with, our component will not use any special permissions, so you can select none.

Once we’re done with the wizard, we can open our src/index.ts file. By default, our component will add a listener to all page views:

import { ComponentSettings, Manager } from '@managed-components/types'

export default async function (manager: Manager, settings: ComponentSettings) {
  manager.addEventListener('pageview', event => {
    // do the things
  })
}

Let’s edit the comment line so that we can see whenever a page view happens. Note we also prefixed settings with a _ because we’re not using it now:

import { ComponentSettings, Manager } from '@managed-components/types'

export default async function (manager: Manager, _settings: ComponentSettings) {
  manager.addEventListener('pageview', event => {
    console.log(`New pageview at ${event.client.url}`)
  })
}

With these changes, the component will print the current URL whenever a page is viewed on the website. Before trying it out, we need to build our component. In the folder of your component run npm i && npm run build. Then, use the namespace of your component to add it to your webcm.config.ts file and restart WebCM:

export default {
  components: [
    {
      name: 'demo',
      permissions: [
        'access_client_kv',
        'provide_server_functionality',
        'provide_widget',
        'serve_static_files',
        'client_network_requests',
      ],
    },
    {
      name: 'google-analytics',
      settings: { 'tid': 'UA-123456' },
      permissions: [
        'access_client_kv',
      ],
    },
    {
      name: 'your-component-namespace',
      settings: {},
      permissions: [],
    },
  ],
  target: 'http://127.0.0.1:8000',
  hostname: 'localhost',
  trackPath: '/webcm/track',
  ecommerceEventsPath: '/webcm/ecommerce',
  clientEventsPath: '/webcm/system',
  port: 8080
}

This is a very simple component, but it shows how easy it is to build functionality that was previously only available in the browser. You can easily extend your component: use fetch next to the console.log statement and send information to your own analytics warehouse whenever a pageview happens on your site. Read about all the other Managed Components APIs to create widgets, listen to clicks, store cookies, use cache, and much more. These APIs allow you to build richer tools than it was ever possible before.

Your tool is better as a Managed Component

When we started working on Managed Components, many people were asking what would be the motivation of a tool vendor to build a Managed Component. During these last few months, we’ve learned that vendors are often excited about Managed Components for the same reasons we are – it provides a safe way to use their tools, and a streamlined way to integrate their tools in websites. Customers care deeply for these things, so having a Managed Component means that customers are more likely to try out your technology. Vendors will also get huge discoverability benefits, as their tools could be featured in the Cloudflare Zaraz dashboard, exposing them to tens of thousands of Zaraz-enabled websites. We are getting a lot of interest from major vendors in building a Managed Component, and we’re doing our best in actively supporting them in the process. If your company is interested in having a Managed Component, contact us.

We strongly believe that Managed Components can change the way third-party tools are used online. This is only the beginning of making them faster, secure and private. Together with users, and vendors, we will work on constantly improving the capabilities of Managed Components as a community, for the benefit of every user of the World Wide Web. To get started with building your Managed Component, head to managedcomponents.dev and start building. Our team is available to help you at [email protected].

Securing Open-Source Software

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/07/securing-open-source-software.html

Good essay arguing that open-source software is a critical national-security asset and needs to be treated as such:

Open source is at least as important to the economy, public services, and national security as proprietary code, but it lacks the same standards and safeguards. It bears the qualities of a public good and is as indispensable as national highways. Given open source’s value as a public asset, an institutional structure must be built that sustains and secures it.

This is not a novel idea. Open-source code has been called the “roads and bridges” of the current digital infrastructure that warrants the same “focus and funding.” Eric Brewer of Google explicitly called open-source software “critical infrastructure” in a recent keynote at the Open Source Summit in Austin, Texas. Several nations have adopted regulations that recognize open-source projects as significant public assets and central to their most important systems and services. Germany wants to treat open-source software as a public good and launched a sovereign tech fund to support open-source projects “just as much as bridges and roads,” and not just when a bridge collapses. The European Union adopted a formal open-source strategy that encourages it to “explore opportunities for dedicated support services for open source solutions [it] considers critical.”

Designing an institutional framework that would secure open source requires addressing adverse incentives, ensuring efficient resource allocation, and imposing minimum standards. But not all open-source projects are made equal. The first step is to identify which projects warrant this heightened level of scrutiny—projects that are critical to society. CISA defines critical infrastructure as industry sectors “so vital to the United States that [its] incapacity or destruction would have a debilitating impact on our physical or economic security or public health or safety.” Efforts should target the open-source projects that share those features.

Introducing even more security enhancements to npm

Post Syndicated from Myles Borins original https://github.blog/2022-07-26-introducing-even-more-security-enhancements-to-npm/

The JavaScript community downloads over 5 billion packages from npm a day, and we at GitHub recognize how important it is that developers can do so with confidence. As stewards of the npm registry, it’s important that we continue to invest in improvements that increase developer trust and the overall security of the registry itself.

Today, we are announcing the general availability of an enhanced 2FA experience on npm, as well as sharing additional investments we’ve made to the verification process of accounts and packages.

The following improvements to npm are available today, including:

  • A streamlined login and publishing experience with the npm CLI.
  • The ability to connect GitHub and Twitter accounts to npm.
  • All packages on npm have been re-signed and we’ve added a new npm CLI command to audit package integrity.

Streamlined login and publishing experience

Account security is significantly improved by adopting 2FA, but if the experience adds too much friction, we can’t expect customers to adopt it. We recently announced a variety of enhancements to the npm registry to make 2FA adoption easier for developers—in a public beta release. Early adopters of our new 2FA experience shared feedback around the process of logging in and publishing with the npm CLI, and we recognized there was room for improvement. Our initial design was created to be backwards compatible with npm 6 and other clients; in fact the Yarn project was able to backport support for our new experience to Yarn 1 in less than 10 lines of code!

We’ve been hard at work making the CLI experience better than ever based on this feedback, and the improved login and publish experience is now available in npm 8.15.0 today. With the new experience, users will benefit from:

  • Login and publish authentication are managed in the browser.
  • Login can use an existing session only prompting for your second factor or email verification OTP to create a new session.
  • Publish now supports “remember me for 5 minutes” and allows for subsequent publishes from the same IP + access token to avoid the 2FA prompt for a 5-minute period. This is especially useful when publishing from a npm workspace.

It is currently opt-in with the --auth-type=web flag and will be the default experience in npm 9.


npm login --auth-type=web npm publish --auth-type=web

npm login --auth-type=web

These improved experiences will make it easier for users to secure their accounts. A secure account is the beginning of a secure ecosystem. Check out our documentation to learn more about 2FA in npm.

Connecting GitHub and Twitter Accounts to npm


Screenshot of account recovery options on npm

Developers have been able to include their GitHub and Twitter handles on their npm profiles for almost as long as npm accounts have been available. This data has been helpful to connect the identity of an account on npm to an identity on other platforms; however this data has historically been a free-form text field that wasn’t validated or verified.

That’s why today we are launching the ability to link your npm account to your GitHub and Twitter accounts. Linking of these accounts is performed via official integrations with both GitHub and Twitter and ensures that verified account data are included on npm profiles moving forward. We will no longer be showing the previously unverified GitHub or Twitter data on public user profiles, making it possible for developers to audit identities and trust that an account is who they say they are.

Having a verified link between your identities across platforms significantly improves our ability to do account recovery. This new verified data lays the foundation for automating identity verification as part of account recovery. Over time, we will deprecate this legacy data, but we will continue to honor it for now to ensure that customers do not get locked out of their accounts.

You can verify your packages locally with npm audit signatures

Until today npm users have had to rely on a multi-step process to validate the signature of npm packages. This PGP based process was both complex and required users to have knowledge on cryptographic tools which provided a poor developer experience. Developers relying on this existing process should soon start using the new “audit signatures” command. The PGP keys are set to expire early next year with more details to follow.

Recently, we began work to re-sign all npm packages with new signatures relying on the secure ECDSA algorithm and using an HSM for key management, and you can now rely on this signature to verify the integrity of the packages you install from npm.

We have introduced a new audit signatures command in npm CLI version 8.13.0 and above.

Example of a successful audit signature verification

Example of a successful audit signature verification

The below sample GitHub Actions workflow with audit signature in action.

name: npm Package

on:
  release:
    types: [created]

jobs:
  build:
    runs-on: ubuntu-latest
    steps:
     - uses: actions/checkout@v3

     - uses: actions/setup-node@v3
       with:
        node-version: 16.x
        registry-url: 'https://registry.npmjs.org'

     - run: npm install -g npm

     - run: npm ci

     - run: npm audit signatures

     - run: npm test

     - run: npm publish
       env:
        NODE_AUTH_TOKEN: ${{secrets.npm_token}}

What’s next?

Our primary goal continues to be protecting the npm registry, and our next major milestone will be enforcing 2FA for all high-impact accounts, those that manage packages with more than 1 million weekly downloads or 500 dependents, tripling the number of accounts we will require to adopt a second factor. Prior to this enforcement we will be making even more improvements to our account recovery process, including introducing additional forms of identity verification and automating as much of the process as possible.

Learn more about these features by visiting our documentation:

For questions and comments, open a discussion in our feedback repository.

AWS Week In Review – July 25, 2022

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/aws-week-in-review-july-25-2022/

A few weeks ago, we hosted the first EMEA AWS Heroes Summit in Milan, Italy. This past week, I had the privilege to join the Americas AWS Heroes Summit in Seattle, Washington, USA. Meeting with our community experts is always inspiring and a great opportunity to learn from each other. During the Summit, AWS Heroes from North America and Latin America shared their thoughts with AWS developer advocates and product teams on topics such as serverless, containers, machine learning, data, and DevTools. You can learn more about the AWS Heroes program here.

AWS Heroes Summit Americas 2022

Last Week’s Launches
Here are some launches that got my attention during the previous week:

Cloudscape Design System – Cloudscape is an open source design system for creating web applications. It was built for and is used by AWS products and services. We created it in 2016 to improve the user experience across web applications owned by AWS services and also to help teams implement those applications faster. If you’ve ever used the AWS Management Console, you’ve seen Cloudscape in action. If you are building a product that extends the AWS Management Console, designing a user interface for a hybrid cloud management system, or setting up an on-premises solution that uses AWS, have a look at Cloudscape Design System.

Cloudscape Design System

AWS re:Post introduces community-generated articles – AWS re:Post gives you access to a vibrant community that helps you become even more successful on AWS. Expert community members can now share technical guidance and knowledge beyond answering questions through the Articles feature. Using this feature, community members can share best practices and troubleshooting processes and address customer needs around AWS technology in greater depth. The Articles feature is unlocked for community members who have achieved Rising Star status on re:Post or subject matter experts who built their reputation in the community based on their contributions and certifications. If you have a Rising Star status on re:Post, start writing articles now! All other members can unlock Rising Star status through community contributions or simply browse available articles today on re:Post.

AWS re:Post

AWS Lambda announces support for attribute-based access control (ABAC) and new IAM condition key – You can now use attribute-based access control (ABAC) with AWS Lambda to control access to functions within AWS Identity and Access Management (IAM) using tags. ABAC is an authorization strategy that defines access permissions based on attributes. In AWS, these attributes are called tags. With ABAC, you can scale an access control strategy by setting granular permissions with tags without requiring permissions updates for every new user or resource as your organization scales. Read this blog post by Julian Wood and Chris McPeek to learn more.

AWS Lambda also announced support for lambda:SourceFunctionArn, a new IAM condition key that can be used for IAM policy conditions that specify the Amazon Resource Name (ARN) of the function from which a request is made. You can use the Condition element in your IAM policy to compare the lambda:SourceFunctionArn condition key in the request context with values that you specify in your policy. This allows you to implement advanced security controls for the AWS API calls taken by your Lambda function code. For more details, have a look at the Lambda Developer Guide.

Amazon Fraud Detector launches Account Takeover Insights (ATI) – Amazon Fraud Detector now supports an Account Takeover Insights (ATI) model, a low-latency fraud detection machine learning model specifically designed to detect accounts that have been compromised through stolen credentials, phishing, social engineering, or other forms of account takeover. The ATI model is designed to detect up to four times more ATI fraud than traditional rules-based account takeover solutions while minimizing the level of friction for legitimate users. To learn more, have a look at the Amazon Fraud Detector documentation.

Amazon EMR on EC2 clusters (EMR Clusters) introduces more fine-grained access controls – Previously, all jobs running on an EMR cluster used the IAM role associated with the EMR cluster’s EC2 instances to access resources. This role is called the EMR EC2 instance profile. With the new runtime roles for Amazon EMR Steps, you can now specify a different IAM role for your Apache Spark and Hive jobs, scoping down access at a job level. This simplifies access controls on a single EMR cluster that is shared between multiple tenants, wherein each tenant is isolated using IAM roles. You can now also enforce table and column permissions based on your Amazon EMR runtime role to manage your access to data lakes with AWS Lake Formation. For more details, read the What’s New post.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Here are some additional news and customer stories you may find interesting:

AWS open-source news and updates – My colleague Ricardo Sueiras writes this weekly open-source newsletter in which he highlights new open-source projects, tools, and demos from the AWS Community. Read edition #121 here.

AI Use Case Explorer – If you are interested in AI use cases, have a look at the new AI Use Case Explorer. You can search over 100 use cases and 400 customer success stories by industry, business function, and the business outcome you want to achieve.

Bayer centralizes and standardizes data from the carbon program using AWS – To help Brazilian farmers adopt climate-smart agricultural practices and reduce carbon emissions in their activities, Bayer created the Carbon Program, which aims to build carbon-neutral agriculture practices. Learn how Bayer uses AWS to centralize and standardize the data received from the different partners involved in the project in this Bayer case study.

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

AWS re:Inforce 2022 – The event will be held this week in person on July 26 and 27 in Boston, Massachusetts, USA. You can watch the keynote and leadership sessions online for free. AWS On Air will also stream live from re:Inforce.

AWS SummitAWS Global Summits – AWS Global Summits are free events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Registrations are open for the following AWS Summits in August:
Imagine Conference 2022IMAGINE 2022 – The IMAGINE 2022 conference will take place on August 3 at the Seattle Convention Center, Washington, USA. It’s a no-cost event that brings together education, state, and local leaders to learn about the latest innovations and best practices in the cloud. You can register here.
I’ll be speaking at Data Con LA on August 13–14 in Los Angeles, California, USA. Feel free to say “Hi!” if you’re around. And if you happen to be at Ray Summit on August 23–24 in San Francisco, California, USA, stop by the AWS booth. I’ll be there to discuss all things Ray on AWS.

That’s all for this week. Check back next Monday for another Week in Review!

– Antje

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

AWS Week in Review – July 4, 2022

Post Syndicated from Marcia Villalba original https://aws.amazon.com/blogs/aws/aws-week-in-review-july-04-2022/

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Summer has arrived in Finland, and these last few days have been hotter than in the Canary Islands! Today in the US it is Independence Day. I hope that if you are celebrating, you’re having a great time. This week I’m very excited about some developer experience and artificial intelligence launches.

Last Week’s Launches
Here are some launches that got my attention during the previous week:

AWS SAM Accelerate is now generally available – SAM Accelerate is a new capability of the AWS Serverless Application Model CLI, which makes it easier for serverless developers to test code changes against the cloud. You can do a hot swap of code directly in the cloud when making a change in your local development environment. This allows you to develop applications faster. Learn more about this launch in the What’s New post.

Amplify UI for React is generally available – Amplify UI is an open-source UI library that helps developers build cloud-native applications. Amplify UI for React comes with over 35 components that you can use, an authentication component that allows you to connect to your backend with no extra configuration, theming for your components. You can also build your UI using Figma. Check the Amplify UI for React site to learn more about all the capabilities offered.

Amazon Connect has new announcements – First, Amazon Connect added support to personalize the flows of the customer experience using Amazon Lex sentiment analysis. It also added support to branch out the flows depending on Amazon Lex confidence scores. Lastly, it added confidence scores to Amazon Connect Customer Profiles to help companies merge duplicate customer records.

Amazon QuickSight – QuickSight authors can now learn and experience Q before signing up. Authors can choose from six different sample topics and explore different visualizations. In addition, QuickSight now supports Level Aware Calculations (LAC) and rolling date functionality. These two new features bring flexibility and simplification to customers to build advanced calculation and dashboards.

Amazon SageMaker – RStudio on SageMaker now allows you to bring your own development environment in a custom image. RStudio on SageMaker is a fully managed RStudio Workbench in the cloud. In addition, SageMaker added four new tabular data modeling algorithms: LightGBM, CatBoost, AutoGluon-Tabular, and TabTransformer to the existing set of built-in algorithms, pre-trained models and pre-built solution templates it provides.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Some other updates and news that you may have missed:

AWS Support announced an improved experience when creating a case – There is a new interface for creating support cases in the AWS Support Center console. Now you can create a case with a simplified three-step process that guides you through the flow. Learn more about this new process in the What’s new post.

New AWS Step Functions workflows collection on Serverless Land – The Step Functions workflows collection is a new experience that makes it easier to discover, deploy, and share AWS Step Functions workflows. In this collection, you can find opinionated templates that implement the best practices to build using Step Functions. Learn more about this new collection in Ben’s blog post.

Podcast Charlas Técnicas de AWS – If you understand Spanish, this podcast is for you. Podcast Charlas Técnicas is one of the official AWS Podcasts in Spanish, which shares a new episode ever other week. The podcast is meant for builders, and it shares stories about how customers implement and learn AWS, how to architect applications, and how to use new services. You can listen to all the episodes directly from your favorite podcast app or from the AWS Podcasts en español website.

AWS open-source news and updates – A newsletter curated by my colleague Ricardo brings you the latest open-source projects, posts, events, and more.

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

AWS Summit New York – Join us on July 12 for the in-person AWS Summit. You can register on the AWS Summit page for free.

AWS re:Inforce – This is an in-person learning conference with a focus on security, compliance, identity, and privacy. You can register now to access hundreds of technical sessions, and other content. It will take place July 26 and 27 in Boston, MA.

That’s all for this week. Check back next Monday for another Week in Review!

— Marcia

Improve Git monorepo performance with a file system monitor

Post Syndicated from Jeff Hostetler original https://github.blog/2022-06-29-improve-git-monorepo-performance-with-a-file-system-monitor/

If you have a monorepo, you’ve probably already felt the pain of slow Git commands, such as git status and git add. These commands are slow because they need to search the entire worktree looking for changes. When the worktree is very large, Git needs to do a lot of work.

The Git file system monitor (FSMonitor) feature can speed up these commands by reducing the size of the search, and this can greatly reduce the pain of working in large worktrees. For example, this chart shows status times dropping to under a second on three different large worktrees when FSMonitor is enabled!

In this article, I want to talk about the new builtin FSMonitor git fsmonitor--daemon added in Git version 2.37.0. This is easy to set up and use since it is “in the box” and does not require any third-party tooling nor additional software. It only requires a config change to enable it. It is currently available on macOS and Windows.

To enable the new builtin FSMonitor, just set core.fsmonitor to true. A daemon will be started automatically in the background by the next Git command.

FSMonitor works well with core.untrackedcache, so we’ll also turn it on for the FSMonitor test runs. We’ll talk more about the untracked-cache later.

$ time git status
On branch main
Your branch is up to date with 'origin/main'.

It took 5.25 seconds to enumerate untracked files. 'status -uno'
may speed it up, but you have to be careful not to forget to add
new files yourself (see 'git help status').
nothing to commit, working tree clean

real    0m17.941s
user    0m0.031s
sys     0m0.046s

$ git config core.fsmonitor true
$ git config core.untrackedcache true

$ time git status
On branch main
Your branch is up to date with 'origin/main'.

It took 6.37 seconds to enumerate untracked files. 'status -uno'
may speed it up, but you have to be careful not to forget to add
new files yourself (see 'git help status').
nothing to commit, working tree clean

real    0m19.767s
user    0m0.000s
sys     0m0.078s

$ time git status
On branch main
Your branch is up to date with 'origin/main'.

nothing to commit, working tree clean

real    0m1.063s
user    0m0.000s
sys     0m0.093s

$ git fsmonitor--daemon status
fsmonitor-daemon is watching 'C:/work/chromium'

_Note that when the daemon first starts up, it needs to synchronize with the state of the index, so the next git status command may be just as slow (or slightly slower) than before, but subsequent commands should be much faster.

In this article, I’ll introduce the new builtin FSMonitor feature and explain how it improves performance on very large worktrees.

How FSMonitor improves performance

Git has a “What changed while I wasn’t looking?” problem. That is, when you run a command that operates on the worktree, such as git status, it has to discover what has changed relative to the index. It does this by searching the entire worktree. Whether you immediately run it again or run it again tomorrow, it has to rediscover all of that same information by searching again. Whether you edit zero, one, or a million files in the mean time, the next git status command has to do the same amount of work to rediscover what (if anything) has changed.

The cost of this search is relatively fixed and is based upon the number of files (and directories) present in the worktree. In a monorepo, there might be millions of files in the worktree, so this search can be very expensive.

What we really need is a way to focus on the changed files without searching the entire worktree.

How FSMonitor works

FSMonitor is a long-running daemon or service process.

  • It registers with the operating system to receive change notification events on files and directories.
  • It adds the pathnames of those files and directories to an in-memory, time-sorted queue.
  • It listens for IPC connections from client processes, such as git status.
  • It responds to client requests for a list of files and directories that have been modified recently.

FSMonitor must continuously watch the worktree to have a complete view of all file system changes, especially ones that happen between Git commands. So it must be a long-running daemon or service process and not associated with an individual Git command instance. And thus, it cannot be a traditional Git hook (child) process. This design does allow it to service multiple (possibly concurrent) Git commands.

FSMonitor Synchronization

FSMonitor has the concept of a “token”:

  • A token is an opaque string defined by FSMonitor and can be thought of as a globally unique sequence number or timestamp.
  • FSMonitor creates a new token whenever file system events happen.
  • FSMonitor groups file system changes into sets by these ordered tokens.
  • A Git client command sends a (previously generated) token to FSMonitor to request the list of pathnames that have changed, since FSMonitor created that token.
  • FSMonitor includes the current token in every response. The response contains the list of pathnames that changed between the sent and received tokens.

git status writes the received token into the index with other FSMonitor data before it exits. The next git status command reads the previous token (along with the other FSMonitor data) and asks FSMonitor what changed since the previous token.

Earlier, I said a token is like a timestamp, but it also includes other fields to prevent incomplete responses:

  • The FSMonitor process id (PID): This identifies the daemon instance that created the token. If the PID in a client’s request token does not match the currently running daemon, we must assume that the client is asking for data on file system events generated before the current daemon instance was started.
  • A file system synchronization id (SID): This identifies the most recent synchronization with the file system. The operating system may drop file system notification events during heavy load. The daemon itself may get overloaded, fall behind, and drop events. Either way, events were dropped, and there is a gap in our event data. When this happens, the daemon must “declare bankruptcy” and (conceptually) restart with a new SID. If the SID in a client’s request token does not match the daemon’s curent SID, we must assume that the client is asking for data spanning such a resync.

In both cases, a normal response from the daemon would be incomplete because of gaps in the data. Instead, the daemon responds with a trivial (“assume everything was changed”) response and a new token. This will cause the current Git client command to do a regular scan of the worktree (as if FSMonitor were not enabled), but let future client commands be fast again.

Types of files in your worktree

When git status examines the worktree, it looks for tracked, untracked, and ignored files.

Tracked files are files under version control. These are files that Git knows about. These are files that Git will create in your worktree when you do a git checkout. The file in the worktree may or may not match the version listed in the index. When different, we say that there is an unstaged change. (This is independent of whether the staged version matches the version referenced in the HEAD commit.)

Untracked files are just that: untracked. They are not under version control. Git does not know about them. They may be temporary files or new source files that you have not yet told Git to care about (using git add).

Ignored files are a special class of untracked files. These are usually temporary files or compiler-generated files. While Git will ignore them in commands like git add, Git will see them while searching the worktree and possibly slow it down.

Normally, git status does not print ignored files, but we’ll turn it on for this example so that we can see all four types of files.

$ git status --ignored
On branch master
Changes to be committed:
  (use "git restore --staged <file>..." to unstage)
    modified:   README

Changes not staged for commit:
  (use "git add <file>..." to update what will be committed)
  (use "git restore <file>..." to discard changes in working directory)
    modified:   README
    modified:   main.c

Untracked files:
  (use "git add <file>..." to include in what will be committed)
    new-file.c

Ignored files:
  (use "git add -f <file>..." to include in what will be committed)
    new-file.obj

The expensive worktree searches

During the worktree search, Git treats tracked and untracked files in two distinct phases. I’ll talk about each phase in detail in later sections.

  1. In “refresh_index,” Git looks for unstaged changes. That is, changes to tracked files that have not been staged (added) to the index. This potentially requires looking at each tracked file in the worktree and comparing its contents with the index version.
  2. In “untracked,” Git searches the worktree for untracked files and filters out tracked and ignored files. This potentially requires completely searching each subdirectory in the worktree.

There is a third phase where Git compares the index and the HEAD commit to look for staged changes, but this phase is very fast, because it is inspecting internal data structures that are designed for this comparision. It avoids the significant number of system calls that are required to inspect the worktree, so we won’t worry about it here.

A detailed example

The chart in the introduction showed status times before and after FSMonitor was enabled. Let’s revisit that chart and fill in some details.

I collected performance data for git status on worktrees from three large repositories. There were no modified files, and git status was clean.

  1. The Chromium repository contains about 400K files and 33K directories.
  2. A synthetic repository containing 1M files and 111K directories.
  3. A synthetic repository containing 2M files and 111K directories.

Here we can see that when FSMonitor is not present, the commands took from 17 to 85 seconds. However, when FSMonitor was enabled the commands took less than 1 second.

Each bar shows the total run time of the git status commands. Within each bar, the total time is divided into parts based on performance data gathered by Git’s trace2 library to highlight the important or expensive steps within the commands.

Worktree Files refresh_index

with Preload

Untracked

without Untracked-Cache

Remainder Total
Chromium 393K 12.3s 5.1s 0.16s 17.6s
Synthetic 1M 1M 30.2s 10.5s 0.36s 41.1s
Synthetic 2M 2M 73.2s 11.2s 0.64s 85.1s

The top three bars are without FSMonitor. We can see that most of the time was spent in the refresh_index and untracked columns. I’ll explain what these are in a minute. In the remainder column, I’ve subtracted those two from the total run time. This portion barely shows up on these bars, so the key to speeding up git status is to attack those two phases.

The bottom three bars on the above chart have FSMonitor and the untracked-cache enabled. They show a dramatic performance improvement. On this chart these bars are barely visible, so let’s zoom in on them.

This chart rescales the FSMonitor bars by 100X. The refresh_index and untracked columns are still present but greatly reduced thanks to FSMonitor.

Worktree Files refresh_index

with FSMonitor

Untracked

with FSMonitor

and Untracked-Cache

Remainder Total
Chromium 393K 0.024s 0.519s 0.284s 0.827s
Synthetic 1M 1M 0.050s 0.112s 0.428s 0.590s
Synthetic 2M 2M 0.096s 0.082s 0.572s 0.750s

This is bigger than just status

So far I’ve only talked about git status, since it is the command that we probably use the most and are always thinking about when talking about performance relative to the state and size of the worktree. But it is just one of many affected commands:

  • git diff does the same search, but uses the changed files it finds to print a difference in the worktree and your index.
  • git add . does the same search, but it stages each changed file it finds.
  • git restore and git checkout do the same search to decide the files to be replaced.

So, for simplicity, I’ll just talk about git status, but keep in mind that this approach benefits many other commands, since the cost of actually staging, overwriting, or reporting the change is relatively trivial by comparison — the real performance cost in these commands (as the above charts show) is the time it takes to simply find the changed files in the worktree.

Phase 1: refresh_index

The index contains an “index entry” with information for each tracked file. The git ls-files command can show us what that list looks like. I’ll truncate the output to only show a couple of files. In a monorepo, this list might contain millions of entries.

$ git ls-files --stage --debug
[...]
100644 7ce4f05bae8120d9fa258e854a8669f6ea9cb7b1 0   README.md
  ctime: 1646085519:36302551
  mtime: 1646085519:36302551
  dev: 16777220 ino: 180738404
  uid: 502  gid: 20
  size: 3639    flags: 0
[...]
100644 5f1623baadde79a0771e7601dcea3c8f2b989ed9 0   Makefile
  ctime: 1648154224:994917866
  mtime: 1648154224:994917866
  dev: 16777221 ino: 182328550
  uid: 502  gid: 20
  size: 110149  flags: 0
[...]

Scanning tracked files for unstaged changes

Let’s assume at the beginning of refresh_index that all index entries are “unmarked” — meaning that we don’t know yet whether or not the worktree file contains an unstaged change. And we “mark” an index entry when we know the answer (either way).

To determine if an individual tracked file has an unstaged change, it must be “scanned”. That is, Git must read, clean, hash the current contents of the file, and compare the computed hash value with the hash value stored in the index. If the hashes are the same, we mark the index entry as “valid”. If they are different, we mark it as an unstaged change.

In theory, refresh_index must repeat this for each tracked file in the index.

As you can see, each individual file that we have to scan will take time and if we have to do a “full scan”, it will be very slow, especially if we have to do it for millions of files. For example, on the Chromium worktree, when I forced a full scan it took almost an hour.

Worktree Files Full Scan
Chromium 393K 3072s

refresh_index shortcuts

Since doing a full scan of the worktree is so expensive, Git has developed various shortcuts to avoid scanning whenever possible to increase the performance of refresh_index.

For discussion purposes, I’m going to describe them here as independent steps rather than somewhat intertwined steps. And I’m going to start from the bottom, because the goal of each shortcut is to look at unmarked index entries, mark them if they can, and make less work for the next (more expensive) step. So in a perfect world, the final “full scan” would have nothing to do, because all of the index entries have already been marked, and there are no unmarked entries remaining.

In the above chart, we can see the cummulative effects of these shortcuts.

Shortcut: refresh_index with lstat()

The “lstat() shortcut” was created very early in the Git project.

To avoid actually scanning every tracked file on every git status command, Git relies on a file’s last modification time (mtime) to tell when a file was last changed. File mtimes are updated when files are created or edited. We can read the mtime using the lstat() system call.

When Git does a git checkout or git add, it writes each worktree file’s current mtime into its index entry. These serve as the reference mtimes for future git status commands.

Then, during a later git status, Git checks the current mtime against the reference mtime (for each unmarked file). If they are identical, Git knows that the file content hasn’t changed and marks the index entry valid (so that the next step will avoid it). If the mtimes are different, this step leaves the index entry unmarked for the next step.

Worktree Files refresh_index with lstat()
Chromium 393K 26.9s
Synthetic 1M 1M 66.9s
Synthetic 2M 2M 136.6s

The above table shows the time in seconds taken to call lstat() on every file in the worktree. For the Chromium worktree, we’ve cut the time of refresh_index from 50 minutes to 27 seconds.

Using mtimes is much faster than always scanning each file, but Git still has to lstat() every tracked file during the search, and that can still be very slow when there are millions of files.

In this experiment, there were no modifications in the worktree, and the index was up to date, so this step marked all of the index entries as valid and the “scan all unmarked” step had nothing to do. So the time reported here is essentially just the time to call lstat() in a loop.

This is better than before, but even though we are only doing an lstat(), git status is still spending more than 26 seconds in this step. We can do better.

Shortcut: refresh_index with preload

The core.preloadindex config option is an optional feature in Git. The option was introduced in version 1.6 and was enabled by default in 2.1.0 on platforms that support threading.

This step partitions the index into equal-sized chunks and distributes it to multiple threads. Each thread does the lstat() shortcut on their partition. And like before, index entries with different mtimes are left unmarked for the next step in the process.

The preload step does not change the amount of file scanning that we need to do in the final step, it just distributes the lstat() calls across all of your cores.

Worktree Files refresh_index with Preload
Chromium 393K 12.3s
Synthetic 1M 1M 30.2s
Synthetic 2M 2M 73.2s

With the preload shortcut git status is about twice as fast on my 4-core Windows laptop, but it is still expensive.

Shortcut: refresh_index with FSMonitor

When FSMonitor is enabled:

  1. The git fsmonitor--daemon is started in the background and listens for file system change notification events from the operating system for files within the worktree. This includes file creations, deletions, and modifications. If the daemon gets an event for a file, that file probably has an updated mtime. Said another way, if a file mtime changes, the daemon will get an event for it.
  2. The FSMonitor index extension is added to the index to keep track of FSMonitor and git status data between git status commands. The extension contains an FSMonitor token and a bitmap listing the files that were marked valid by the previous git status command (and relative to that token).
  3. The next git status command will use this bitmap to initialize the marked state of the index entries. That is, the previous Git command saved the marked state of the index entries in the bitmap and this command restores them — rather than initializing them all as unmarked.
  4. It will then ask the daemon for a list of files that have had file system events since the token and unmark each of them. FSMonitor tells us the exact set of files that have been modified in some way since the last command, so those are the only files that we should need to visit.

At this point, all of the unchanged files should be marked valid. Only files that may have changed should be unmarked. This sets up the next shortcut step to have very little to do.

Worktree Files Query FSMonitor refresh_index with FSMonitor
Chromium 393K 0.017s 0.024s
Synthetic 1M 1M 0.002s 0.050s
Synthetic 2M 2M 0.002s 0.096s

This table shows that refresh_index is now very fast since we don’t need to any searching. And the time to request the list of files over IPC is well worth the complex setup.

Phase 2: untracked

The “untracked” phase is a search for anything in the worktree that Git does not know about. These are files and directories that are not under version control. This requires a full search of the worktree.

Conceptually, this looks like:

  1. A full recursive enumeration of every directory in the worktree.
  2. Build a complete list of the pathnames of every file and directory within the worktree.
  3. Take each found pathname and do a binary search in the index for a corresponding index entry. If one is found, the pathname can be omitted from the list, because it refers to a tracked file.
    1. On case insensitive systems, such as Windows and macOS, a case insensitive hash table must be constructed from the case sensitive index entries and used to lookup the pathnames instead of the binary search.
  4. Take each remaining pathname and apply .gitignore pattern matching rules. If a match is found, then the pathname is an ignored file and is omitted from the list. This pattern matching can be very expensive if there are lots of rules.
  5. The final resulting list is the set of untracked files.

This search can be very expensive on monorepos and frequently leads to the following advice message:

$ git status
On branch main
Your branch is up to date with 'origin/main'.

It took 5.12 seconds to enumerate untracked files. 'status -uno'
may speed it up, but you have to be careful not to forget to add
new files yourself (see 'git help status').
nothing to commit, working tree clean

Normally, the complete discovery of the set of untracked files must be repeated for each command unless the [core.untrackedcache](https://git-scm.com/docs/git-config#Documentation/git-config.txt-coreuntrackedCache) feature is enabled.

The untracked-cache

The untracked-cache feature adds an extension to the index that remembers the results of the untracked search. This includes a record for each subdirectory, its mtime, and a list of the untracked files within it.

With the untracked-cache enabled, Git still needs to lstat() every directory in the worktree to confirm that the cached record is still valid.

If the mtimes match:

  • Git avoids calling opendir() and readdir() to enumerate the files within the directory,
  • and just uses the existing list of untracked files from the cache record.

If the mtimes don’t match:

  • Git needs to invalidate the untracked-cache entry.
  • Actually open and read the directory contents.
  • Call lstat() on each file or subdirectory within the directory to determine if it is a file or directory and possibly invalidate untracked-cache entries for any subdirectories.
  • Use the file pathname to do tracked file filtering.
  • Use the file pathname to do ignored file filtering
  • Update the list of untracked files in the untracked-cache entry.

How FSMonitor helps the untracked-cache

When FSMonitor is also enabled, we can avoid the lstat() calls, because FSMonitor tells us the set of directories that may have an updated mtime, so we don’t need to search for them.

Worktree Files Untracked

without Untracked-Cache

Untracked

with Untracked-Cache

Untracked

with Untracked-Cache

and FSMonitor

Chromium 393K 5.1s 2.3s 0.83s
Synthetic 1M 1M 10.5s 6.3s 0.59s
Synthetic 2M 2M 11.2s 6.6s 0.75s

By itself, the untracked-cache feature gives roughly a 2X speed up in the search for untracked files. Use both the untracked-cache and FSMonitor, and we see a 10X speedup.

A note about ignored files

You can improve Git performance by not storing temporary files, such as compiler intermediate files, inside your worktree.

During the untracked search, Git first eliminates the tracked files from the candidate untracked list using the index. Git then uses the .gitignore pattern matching rules to eliminate the ignored files. Git’s performance will suffer if there are many rules and/or many temporary files.

For example, if there is a *.o for every source file and they are stored next to their source files, then every build will delete and recreate one or more object files and cause the mtime on their parent directories to change. Those mtime changes will cause git status to invalidate the corresponding untracked-cache entries and have to re-read and re-filter those directories — even if no source files actually changed. A large number of such temporary and uninteresting files can greatly affect the performance of these Git commands.

Keeping build artifacts out of your worktree is part of the philosophy of the Scalar Project. Scalar introduced Git tooling to help you keep your worktree in <repo-name>/src/ to make it easier for you to put these other files in <repo-name>/bin/ or <repo-name>/packages/, for example.

A note about sparse checkout

So far, we’ve talked about optimizations to make Git work smarter and faster on worktree-related operations by caching data in the index and in various index extensions. Future commands are faster, because they don’t have to rediscover everything and therefore can avoid repeating unnecessary or redundant work. But we can only push that so far.

The Git sparse checkout feature approaches worktree performance from another angle. With it, you can ask Git to only populate the files that you need. The parts that you don’t need are simply not present. For example, if you only need 10% of the worktree to do your work, why populate the other 90% and force Git to search through them on every command?

Sparse checkout speeds the search for unstaged changes in refresh_index because:

  1. Since the unneeded files are not actually present on disk, they cannot have unstaged changes. So refresh_index can completely ignore them.
  2. The index entries for unneeded files are pre-marked during git checkout with the skip-worktree bit, so they are never in an “unmarked” state. So those index entries are excluded from all of the refresh_index loops.

Sparse checkout speeds the search for untracked files because:

  1. Since Git doesn’t know whether a directory contains untracked files until it searches it, the search for untracked files must visit every directory present in the worktree. Sparse checkout lets us avoid creating entire sub-trees or “cones” from the worktree. So there are fewer directories to visit.
  2. The untracked-cache does not need to create, save, and restore untracked-cache entries for the unpopulated directories. So reading and writing the untracked-cache extension in the index is faster.

External file system monitors

So far we have only talked about Git’s builtin FSMonitor feature. Clients use the simple IPC interface to communicate directly with git fsmonitor--daemon over a Unix domain socket or named pipe.

However, Git added support for an external file system monitor in version 2.16.0 using the core.fsmonitor hook. Here, clients communicate with a proxy child helper process through the hook interface, and it communicates with an external file system monitor process.

Conceptually, both types of file system monitors are identical. They include a long-running process that listens to the file system for changes and are able to respond to client requests for a list of recently changed files and directories. The response from both are used identically to update and modify the refresh_index and untracked searches. The only difference is in how the client talks to the service or daemon.

The original hook interface was useful, because it allowed Git to work with existing off-the-shelf tools and allowed the basic concepts within Git to be proven relatively quickly, confirm correct operation, and get a quick speed up.

Hook protocol versions

The original 2.16.0 version of the hook API used protocol version 1. It was a timestamp-based query. The client would send a timestamp value, expressed as nanoseconds since January 1, 1970, and expect a list of the files that had changed since that timestamp.

Protocol version 1 has several race conditions and should not be used anymore. Protocol version 2 was added in 2.26.0 to address these problems.

Protocol version 2 is based upon opaque tokens provided by the external file system monitor process. Clients make token-based queries that are relative to a previously issued token. Instead of making absolute requests, clients ask what has changed since their last request. The format and content of the token is defined by the external file system monitor, such as Watchman, and is treated as an opaque string by Git client commands.

The hook protocol is not used by the builtin FSMonitor.

Using Watchman and the sample hook script

Watchman is a popular external file system monitor tool and a Watchman-compatible hook script is included with Git and copied into new worktrees during git init.

To enable it:

  1. Install Watchman on your system.
  2. Tell Watchman to watch your worktree:
$ watchman watch .
{
    "version": "2022.01.31.00",
    "watch": "/Users/jeffhost/work/chromium",
    "watcher": "fsevents"
}

  1. Install the sample hook script to teach Git how to talk to Watchman:
$ cp .git/hooks/fsmonitor-watchman.sample .git/hooks/query-watchman

  1. Tell Git to use the hook:
$ git config core.fsmonitor .git/hooks/query-watchman

Using Watchman with a custom hook

The hook interface is not limited to running shell or Perl scripts. The included sample hook script is just an example implementation. Engineers at Dropbox described how they were able to speed up Git with a custom hook executable.

Final Remarks

In this article, we have seen how a file system monitor can speed up commands like git status by solving the “discovery” problem and eliminating the need to search the worktree for changes in every command. This greatly reduces the pain of working with monorepos.

This feature was created in two efforts:

  1. First, Git was taught to work with existing off-the-shelf tools, like Watchman. This allowed the basic concepts to be proven relatively quickly. And for users who already use Watchman for other purposes, it allows Git to efficiently interoperate with them.
  2. Second, we brought the feature “in the box” to reduce the setup complexity and third-party dependencies, which some users may find useful. It also lets us consider adding Git-specific features that a generic monitoring tool might not want, such as understanding ignored files and omitting them from the service’s response.

Having both options available lets users choose the best solution for their needs.

Regardless of which type of file system monitor you use, it will help make your monorepos more usable.

AWS Week in Review – June 27, 2022

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-week-in-review-june-27-2022/

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

It’s the beginning of a new week, and I’d like to start with a recap of the most significant AWS news from the previous 7 days. Last week was special because I had the privilege to be at the very first EMEA AWS Heroes Summit in Milan, Italy. It was a great opportunity of mutual learning as this community of experts shared their thoughts with AWS developer advocates, product managers, and technologists on topics such as containers, serverless, and machine learning.

Participants at the EMEA AWS Heroes Summit 2022

Last Week’s Launches
Here are the launches that got my attention last week:

Amazon Connect Cases (available in preview) – This new capability of Amazon Connect provides built-in case management for your contact center agents to create, collaborate on, and resolve customer issues. Learn more in this blog post that shows how to simplify case management in your contact center.

Many updates for Amazon RDS and Amazon Aurora – Amazon RDS Custom for Oracle now supports Oracle database 12.2 and 18c, and Amazon RDS Multi-AZ deployments with one primary and two readable standby database instances now supports M5d and R5d instances and is available in more Regions. There is also a Regional expansion for RDS Custom. Finally, PostgreSQL 14, a new major version, is now supported by Amazon Aurora PostgreSQL-Compatible Edition.

AWS WAF Captcha is now generally available – You can use AWS WAF Captcha to block unwanted bot traffic by requiring users to successfully complete challenges before their web requests are allowed to reach resources.

Private IP VPNs with AWS Site-to-Site VPN – You can now deploy AWS Site-to-Site VPN connections over AWS Direct Connect using private IP addresses. This way, you can encrypt traffic between on-premises networks and AWS via Direct Connect connections without the need for public IP addresses.

AWS Center for Quantum Networking – Research and development of quantum computers have the potential to revolutionize science and technology. To address fundamental scientific and engineering challenges and develop new hardware, software, and applications for quantum networks, we announced the AWS Center for Quantum Networking.

Simpler access to sustainability data, plus a global hackathon – The Amazon Sustainability Data Initiative catalog of datasets is now searchable and discoverable through AWS Data Exchange. As part of a new collaboration with the International Research Centre in Artificial Intelligence, under the auspices of UNESCO, you can use the power of the cloud to help the world become sustainable by participating to the Amazon Sustainability Data Initiative Global Hackathon.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
A couple of takeaways from the Amazon re:MARS conference:

Amazon CodeWhisperer (preview) – Amazon CodeWhisperer is a coding companion powered by machine learning with support for multiple IDEs and languages.

Synthetic data generation with Amazon SageMaker Ground Truth – Generate labeled synthetic image data that you can combine with real-world data to create more complete training datasets for your ML models.

Some other updates you might have missed:

AstraZeneca’s drug design program built using AWS wins innovation award – AstraZeneca received the BioIT World Innovative Practice Award at the 20th anniversary of the Bio-IT World Conference for its novel augmented drug design platform built on AWS. More in this blog post.

Large object storage strategies for Amazon DynamoDB – A blog post showing different options for handling large objects within DynamoDB and the benefits and disadvantages of each approach.

Amazon DevOps Guru for RDS under the hood – Some details of how DevOps Guru for RDS works, with a specific focus on its scalability, security, and availability.

AWS open-source news and updates – A newsletter curated by my colleague Ricardo to bring you the latest open-source projects, posts, events, and more.

Upcoming AWS Events
It’s AWS Summits season and here are some virtual and in-person events that might be close to you:

On June 30, the AWS User Group Ukraine is running an AWS Tech Conference to discuss digital transformation with AWS. Join to learn from many sessions including a fireside chat with Dr. Werner Vogels, CTO at Amazon.com.

That’s all from me for this week. Come back next Monday for another Week in Review!

— Danilo

Highlights from Git 2.37

Post Syndicated from Taylor Blau original https://github.blog/2022-06-27-highlights-from-git-2-37/

The open source Git project just released Git 2.37, with features and bug fixes from over 75 contributors, 20 of them new. We last caught up with you on the latest in Git back when 2.36 was released.

To celebrate this most recent release, here’s GitHub’s look at some of the most interesting features and changes introduced since last time.

Before we get into the details of Git 2.37.0, we first wanted to let you know that Git Merge is returning this September. The conference features talks, workshops, and more all about Git and the Git ecosystem. There is still time to submit a proposal to speak. We look forward to seeing you there!

A new mechanism for pruning unreachable objects

In Git, we often talk about classifying objects as either “reachable” or “unreachable”. An object is “reachable” when there is at least one reference (a branch or a tag) from which you can start an object walk (traversing from commits to their parents, from trees into their sub-trees, and so on) and end up at your destination. Similarly, an object is “unreachable” when no such reference exists.

A Git repository needs all of its reachable objects to ensure that the repository is intact. But it is free to discard unreachable objects at any time. And it is often desirable to do just that, particularly when many unreachable objects have piled up, you’re running low on disk space, or similar. In fact, Git does this automatically when running garbage collection.

But observant readers will notice the gc.pruneExpire configuration. This setting defines a “grace period” during which unreachable objects which are not yet old enough to be removed from the repository completely are left alone. This is done in order to mitigate a race condition where an unreachable object that is about to be deleted becomes reachable by some other process (like an incoming reference update or a push) before then being deleted, leaving the repository in a corrupt state.

Setting a small, non-zero grace period makes it much less likely to encounter this race in practice. But it leads us to another problem: how do we keep track of the age of the unreachable objects which didn’t leave the repository? We can’t pack them together into a single packfile; since all objects in a pack share the same modification time, updating any object drags them all forward. Instead, prior to Git 2.37, each surviving unreachable object was written out as a loose object, and the mtime of the individual objects was used to store their age. This can lead to serious problems when there are many unreachable objects which are too new and can’t be pruned.

Git 2.37 introduces a new concept, cruft packs, which allow unreachable objects to be stored together in a single packfile by writing the ages of individual objects in an auxiliary table stored in an *.mtimes file alongside the pack.

While cruft packs don’t eliminate the data race we described earlier, in practice they can help make it much less likely by allowing repositories to prune with a much longer grace period, without worrying about the potential to create many loose objects. To try it out yourself, you can run:

$ git gc --cruft --prune=1.day.ago

and notice that your $GIT_DIR/objects/pack directory will have an additional .mtimes file, storing the ages of each unreachable object written within the last 24 hours

$ ls -1 .git/objects/pack
pack-243103d0f640e0096edb3ef0c842bc5534a9f9a4.idx
pack-243103d0f640e0096edb3ef0c842bc5534a9f9a4.mtimes
pack-243103d0f640e0096edb3ef0c842bc5534a9f9a4.pack
pack-5a827af6f1a793a45c816b05d40dfd4d5f5edf28.idx
pack-5a827af6f1a793a45c816b05d40dfd4d5f5edf28.pack

There’s a lot of detail we haven’t yet covered on cruft packs, so expect a more comprehensive technical overview in a separate blog post soon.

[source]

A builtin filesystem monitor for Windows and macOS

As we have discussed often before, one of the factors that significantly impact Git’s performance is the size of your working directory. When you run git status, for example, Git has to crawl your entire working directory (in the worst case) in order to figure out which files have been modified.

Git has its own cached understanding of the filesystem to avoid this whole-directory traversal in many cases. But it can be expensive for Git to update its cached understanding of the filesystem with the actual state of the disk while you work.

In the past, Git has made it possible to integrate with tools like Watchman via a hook, making it possible to replace Git’s expensive refreshing process with a long-running daemon which tracks the filesystem state more directly.

But setting up this hook and installing a third-party tool can be cumbersome. In Git 2.37, this functionality is built into Git itself on Windows and macOS, removing the need to install an external tool and configure the hook.

You can enable this for your repository by enabling the core.fsmonitor config setting.

$ git config core.fsmonitor true

After setting up the config, an initial git status will take the normal amount of time, but subsequent commands will take advantage of the monitored data and run significantly faster.

The full implementation is impossible to describe completely in this post. Interested readers can follow along later this week with a blog post written by Jeff Hostetler for more information. We’ll be sure to add a link here when that post is published.

[source, source, source, source]

The sparse index is ready for wide use

We previously announced Git’s sparse index feature, which helps speed up Git commands when using the sparse-checkout feature in a large repository.

In case you haven’t seen our earlier post, here’s a brief refresher. Often when working in an extremely large repository, you don’t need the entire contents of your repository present locally in order to contribute. For example, if your company uses a single monorepo, you may only be interested in the parts of that repository that correspond to the handful of products you work on.

Partial clones make it possible for Git to only download the objects that you care about. The sparse index is an equally important component of the equation. The sparse index makes it possible for the index (a key data structure which tracks the content of your next commit, which files have been modified, and more) to only keep track of the parts of your repository that you’re interested in.

When we originally announced the sparse index, we explained how different Git subcommands would have to be updated individually to take advantage of the sparse index. With Git 2.37.0, all of those integrations are now included in the core Git project and available to all users.

In this release, the final integrations were for git show, git sparse-checkout, and git stash. In particular, git stash has the largest performance boost of all of the integrations so far because of how the command reads and writes indexes multiple times in a single process, achieving a near 80% speed-up in certain cases (though see this thread for all of the details).

[source, source, source]

That’s just a sample of changes from the latest release. For more, check out the release notes for 2.37, or any previous version in the Git repository.

Tidbits

Now that we have looked at some of the bigger features in detail, let’s turn to a handful of smaller topics from this release.

  • Speaking of sparse checkouts, this release deprecates the non---cone-mode style of sparse checkout definitions.

    For the uninitiated, the git sparse-checkout command supports two kinds of patterns which dictate which parts of your repository should be checked out: “cone” mode, and “non-cone” mode. The latter, which allows specifying individual files with a .gitignore-style syntax, can be confusing to use correctly, and has performance problems (namely that in the worst case all patterns must try to be matched with all files, leading to slow-downs). Most importantly, it is incompatible with the sparse-index, which brings the performance enhancements of using a sparse checkout to all of the Git commands you’re familiar with.

    For these reasons (and more!), the non---cone mode style of patterns is discouraged, and users are instead encouraged to use --cone mode.

    [source]

  • In our highlights from the last Git release, we talked about more flexible fsync configuration, which made it possible to more precisely define what files Git would explicitly synchronize with fsync() and what strategy it would use to do that synchronization.

    This release brings a new strategy to the list supported by core.fsyncMethod: “batch”, which can provide significant speed-ups on supported filesystems when writing many individual files. This new mode works by staging many updates to the disk’s writeback cache before preforming a single fsync() causing the disk to flush its writeback cache. Files are then atomically moved into place, guaranteeing that they are fsync()-durable by the time they enter the object directory.

    For now, this mode only supports batching loose object writes, and will only be enabled when core.fsync includes the loose-objects value. On a synthetic test of adding 500 files to the repository with git add (each resulting in a new loose object), the new batch mode imposes only a modest penalty over not fsyncing at all.

    On Linux, for example, adding 500 files takes .06 seconds without any fsync() calls, 1.88 seconds with an fsync() after each loose object write, and only .15 seconds with the new batched fsync(). Other platforms display similar speed-ups, with a notable example being Windows, where the numbers are .35 seconds, 11.18 seconds, and just .41 seconds, respectively.

    [source]

  • If you’ve ever wondered, “what’s changed in my repository since yesterday?”, one way you can figure that out is with the --since option, which is supported by all standard revision-walking commands, like log and rev-list.

    This option works by starting with the specified commits, and walking recursively along each commit’s parents, stopping the traversal as soon as it encounters a commit older than the --since date. But in occasional circumstances (particularly when there is) clock skew this can produce confusing results.

    For example, suppose you have three commits, C1, C2, and C3, where C2 is the parent of C3, and C1 is the parent of C2. If both C1 and C3 were written in the last hour, but C2 is a day old (perhaps because the committer’s clock is running slow), then a traversal with --since=1.hour.ago will only show C3, since seeing C2 causes Git to halt its traversal.

    If you expect your repository’s history has some amount of clock skew, then you can use --since-as-filter in place of --since, which only prints commits newer than the specified date, but does not halt its traversal upon seeing an older one.

    [source]

  • If you work with partial clones, and have a variety of different Git remotes, it can be confusing to remember which partial clone filter is attached to which remote.

    Even in a simple example, trying to remember what object filter was used to clone your repository requires this incantation:

    $ git config remote.origin.partialCloneFilter
    

    In Git 2.37, you can now access this information much more readily behind the -v flag of git remote, like so:

    $ git remote -v
    origin    [email protected]:git/git.git (fetch) [tree:0]
    origin    [email protected]:git/git.git (push)
    

    Here, you can easily see between the square-brackets that the remote origin uses a tree:0 filter.

    This work was contributed by Abhradeep Chakraborty, a Google Summer of Code student, who is one of three students participating this year and working on Git.

    [source]

  • Speaking of remote configuration, Git 2.37 ships with support for warning or exiting when it encounters plain-text credentials stored in your configuration with the new transfer.credentialsInUrl setting.

    Storing credentials in plain-text in your repository’s configuration is discouraged, since it forces you to ensure you have appropriately restrictive permissions on the configuration file. Aside from storing the data unencrypted at rest, Git often passes the full URL (including credentials) to other programs, exposing them on systems where other processes have access to arguments list of sensitive processes. In most cases, it is encouraged to use Git’s credential mechanism, or tools like GCM.

    This new setting allows Git to either ignore or halt execution when it sees one of these credentials by setting the transfer.credentialsInUrl to “warn” or “die” respectively. The default, “allow”, does nothing.

    [source, source]

  • If you’ve ever used git add -p to stage the contents of your working tree incrementally, then you may be familiar with git add‘s “interactive mode”, or git add -i, of which git add -p is a sub-mode.

    In addition to “patch” mode, git add -i supports “status”, “update”, “revert”, “add untracked”, “patch”, and “diff”. Until recently, this mode of git add -i was actually written in Perl. This command has been the most recent subject of a long-running effort to port Git commands written in Perl into C. This makes it possible to use Git’s libraries without spawning sub-processes, which can be prohibitively expensive on certain platforms.

    The C reimplementation of git add -i has shipped in releases of Git as early as v2.25.0. In more recent versions, this reimplementation has been in “testing” mode behind an opt-in configuration. Git 2.37 promotes the C reimplementation by default, so Windows users should notice a speed-up when using git add -p.

    [source, source, source, source, source, source, source]

  • Last but not least, there is a lot of exciting work going on for Git developers, too, like improving the localization workflow, improving CI output with GitHub Actions, and reducing memory leaks in internal APIs.

    If you’re interested in contributing to Git, now is a more exciting time than ever to start. Check out this guide for some tips on getting started.

The rest of the iceberg

That’s just a sample of changes from the latest release. For more, check out the release notes for 2.37 or any previous version in the Git repository.

Velociraptor Version 0.6.5: Table Transformations, Multi-Lingual Support, and Better VQL Error-Handling Let You Dig Deeper Than Ever

Post Syndicated from Carlos Canto original https://blog.rapid7.com/2022/06/24/velociraptor-version-0-6-5-table-transformations-multi-lingual-support-and-better-vql-error-handling-let-you-dig-deeper-than-ever/

Velociraptor Version 0.6.5: Table Transformations, Multi-Lingual Support, and Better VQL Error-Handling Let You Dig Deeper Than Ever

Rapid7 is pleased to announce the release of Velociraptor version 0.6.5 – an advanced, open-source digital forensics and incident response (DFIR) tool that enhances visibility into your organization’s endpoints.  This release has been in development and testing for several months now, and we are excited to share its new features and improvements.

Table transformations

Velociraptor collections or hunts are usually post-processed or filtered in Notebooks. This allows users to refine and post-process the data in complex ways. For example, to view only the Velociraptor service from a hunt collecting all services (Windows.System.Services), one would click on the Notebook tab and modify the query by adding a WHERE statement.

Velociraptor Version 0.6.5: Table Transformations, Multi-Lingual Support, and Better VQL Error-Handling Let You Dig Deeper Than Ever
Filtering rows with VQL

In our experience, this ability to quickly filter or sort a table is very common, and sometimes we don’t really need the full power of VQL. In 0.6.5, we introduced table transformations — simple filtering/sorting operations on every table in the GUI.

Velociraptor Version 0.6.5: Table Transformations, Multi-Lingual Support, and Better VQL Error-Handling Let You Dig Deeper Than Ever
Setting simple table transformations

Multi-lingual support

Velociraptor’s community of DFIR professionals is global! We have users from all over the world, and although most users are fluent in English, we wanted to acknowledge our truly international user base by adding internationalization into the GUI. You can now select from a number of popular languages. (Don’t see your language here? We would love additional contributions!)

Velociraptor Version 0.6.5: Table Transformations, Multi-Lingual Support, and Better VQL Error-Handling Let You Dig Deeper Than Ever
Select from a number of popular languages

Here is a screenshot showing our German translations:

Velociraptor Version 0.6.5: Table Transformations, Multi-Lingual Support, and Better VQL Error-Handling Let You Dig Deeper Than Ever
The Velociraptor interface in German

New interface themes

The 0.6.5 release expanded our previous offering of 3 themes into 7, with a selection of light and dark themes. We even have a retro feel ncurses theme that looks like a familiar terminal…

Velociraptor Version 0.6.5: Table Transformations, Multi-Lingual Support, and Better VQL Error-Handling Let You Dig Deeper Than Ever
A stunning retro ‘ncurses’ theme

Error-handling in VQL

Velociraptor is simply a VQL engine – users write VQL artifacts and run these queries on the endpoint.

Previously, it was difficult to tell when VQL encountered an error. Sometimes a missing file is expected, and other times it means something went wrong. From Velociraptor’s point of view, as long as the VQL query ran successfully on the endpoint, the collection was a success. The VQL query can generate logs to provide more information, but the user had to actually look at the logs to determine if there was a problem.

For example, in a hunt parsing a file on the endpoints, it was difficult to tell which of the thousands of machines failed to parse a file. Previously, Velociraptor marked the collection as successful if the VQL query ran – even if it returned no rows because the file failed to parse.

In 0.6.5, there is a mechanism for VQL authors to convey more nuanced information to the user by way of error levels. The VQL log() function was expanded to take a level parameter. When the level is ERROR the collection will be marked as failed in the GUI.

Velociraptor Version 0.6.5: Table Transformations, Multi-Lingual Support, and Better VQL Error-Handling Let You Dig Deeper Than Ever
A failed VQL query

Velociraptor Version 0.6.5: Table Transformations, Multi-Lingual Support, and Better VQL Error-Handling Let You Dig Deeper Than Ever
Query Log messages have their own log level

Custom time zone support

Timestamps are a central part of most DFIR work. Although it is best practice to always work in UTC times, it can be a real pain to have to convert from UTC to local time in your head! Since Velociraptor always uses RFC3389 to represent times unambiguously but for human consumption, it is convenient to represent these times in different local times.

You can now select a more convenient time zone in the GUI by clicking your user preferences and setting the relevant timezone.

Velociraptor Version 0.6.5: Table Transformations, Multi-Lingual Support, and Better VQL Error-Handling Let You Dig Deeper Than Ever
Selecting a custom timezone

The preferred time will be shown in most instances in the UI:

Velociraptor Version 0.6.5: Table Transformations, Multi-Lingual Support, and Better VQL Error-Handling Let You Dig Deeper Than Ever
Time zone selection influences how times are shown

A new MUSL build target

On Linux Go binaries are mostly static but always link to Glibc, which is shipped with the Linux distribution. This means that traditionally Velociraptor had problems running on very old Linux machines (previous to Ubuntu 18.04). We used to build a more compatible version on an old Centos VM, but this was manual and did not support the latest Go compiler.

In 0.6.5, we added a new build target using MUSL – a lightweight Glibc replacement. The produced binary is completely static and should run on a much wider range of Linux versions. This is still considered experimental but should improve the experience on older Linux machines.

Try it out!

If you’re interested in the new features, take Velociraptor for a spin by downloading it from our release page. It’s available for free on GitHub under an open source license.

As always, please file bugs on the GitHub issue tracker or submit questions to our mailing list by emailing [email protected]. You can also chat with us directly on our Discord server.

Learn more about Velociraptor by visiting any of our web and social media channels below:

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

[Security Nation] Steve Micallef of SpiderFoot on Open-Source Intelligence

Post Syndicated from Rapid7 original https://blog.rapid7.com/2022/06/22/security-nation-steve-micallef-of-spiderfoot-on-open-source-intelligence/

[Security Nation] Steve Micallef of SpiderFoot on Open-Source Intelligence

In this episode of Security Nation, Jen and Tod chat with Steve Micallef about SpiderFoot, the open-source intelligence tool of which he is the creator and founder. He tells us how the platform went from a passion project to a fully fledged open-source offering, with a SaaS option to boot, and how it can help security engineers automate tasks and focus on finding the major threats in their data.

Stick around for our Rapid Rundown, where Tod chats with producer Jesse about a new paper that reveals all is not as it seems with CVSS scores.

Steve Micallef

[Security Nation] Steve Micallef of SpiderFoot on Open-Source Intelligence

Steve Micallef is the author of SpiderFoot (www.spiderfoot.net), an open-source OSINT automation platform. You can follow him @binarypool on Twitter.

Show notes

Interview links

Rapid Rundown links

  • Read the full paper, “A Closer Look at CVSS Scores.”
  • Follow the author, Jacques Chester, on Twitter.

Like the show? Want to keep Jen and Tod in the podcasting business? Feel free to rate and review with your favorite podcast purveyor, like Apple Podcasts.

Want More Inspiring Stories From the Security Community?

Subscribe to Security Nation Today

[Security Nation] Phillip Maddux on HoneyDB, the Open-Source Honeypot Data Project

Post Syndicated from Rapid7 original https://blog.rapid7.com/2022/06/08/security-nation-phillip-maddux-on-honeydb-the-open-source-honeypot-data-project/


[Security Nation] Phillip Maddux on HoneyDB, the Open-Source Honeypot Data Project

In this episode of Security Nation, Jen and Tod chat with Phillip Maddux about his project HoneyDB, a site that pulls data together from honeypots around the world in a handy, open-source format for security pros and researchers. He details how his motivations for creating HoneyDB derived from his time in application security and why he thinks open source is such a great format for this kind of project.

No Rapid Rundown this week, since RSAC 2022 has Tod tied up (and several time zones farther from Jen than usual). If you’re in San Francisco for the conference, stop by the Rapid7 booth and say hi!

Phillip Maddux

[Security Nation] Phillip Maddux on HoneyDB, the Open-Source Honeypot Data Project

Phillip Maddux is a staff engineer on the Detection and Response Engineering team at Compass. He has over 15 years of experience in information security, with the majority of that time focused on application security in the financial services sector. Throughout his career, Phillip has been a honeypot enthusiast and is the creator of HoneyDB.io.

Show notes

Interview links

Like the show? Want to keep Jen and Tod in the podcasting business? Feel free to rate and review with your favorite podcast purveyor, like Apple Podcasts.

Want More Inspiring Stories From the Security Community?

Subscribe to Security Nation Today

AWS Week In Review – June 6, 2022

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/aws-week-in-review-june-6-2022/

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

I’ve just come back from a long (extended) holiday weekend here in the US and I’m still catching up on all the AWS launches that happened this past week. I’m particularly excited about some of the data, machine learning, and quantum computing news. Let’s have a look!

Last Week’s Launches
The launches that caught my attention last week are the following:

Amazon EMR Serverless is now generally available – Amazon EMR Serverless allows you to run big data applications using open-source frameworks such as Apache Spark and Apache Hive without configuring, managing, and scaling clusters. The new serverless deployment option for Amazon EMR automatically scales resources up and down to provide just the right amount of capacity for your application, and you only pay for what you use. To learn more, check out Channy’s blog post and listen to The Official AWS Podcast episode on EMR Serverless.

AWS PrivateLink is now supported by additional AWS services – AWS PrivateLink provides private connectivity between your virtual private cloud (VPC), AWS services, and your on-premises networks without exposing your traffic to the public internet. The following AWS services just added support for PrivateLink:

  • Amazon S3 on Outposts has added support for PrivateLink to perform management operations on your S3 storage by using private IP addresses in your VPC. This eliminates the need to use public IPs or proxy servers. Read the June 1 What’s New post for more information.
  • AWS Panorama now supports PrivateLink, allowing you to access AWS Panorama from your VPC without using public endpoints. AWS Panorama is a machine learning appliance and software development kit (SDK) that allows you to add computer vision (CV) to your on-premises cameras. Read the June 2 What’s New post for more information.
  • AWS Backup has added PrivateLink support for VMware workloads, providing direct access to AWS Backup from your VMware environment via a private endpoint within your VPC. Read the June 3 What’s New post for more information.

Amazon SageMaker JumpStart now supports incremental model training and automatic tuning – Besides ready-to-deploy solution templates for common machine learning (ML) use cases, SageMaker JumpStart also provides access to more than 300 pre-trained, open-source ML models. You can now incrementally train all the JumpStart models with new data without training from scratch. Through this fine-tuning process, you can shorten the training time to reach a better model. SageMaker JumpStart now also supports model tuning with SageMaker Automatic Model Tuning from its pre-trained model, solution templates, and example notebooks. Automatic tuning allows you to automatically search for the best hyperparameter configuration for your model.

Amazon Transcribe now supports automatic language identification for multi-lingual audio – Amazon Transcribe converts audio input into text using automatic speech recognition (ASR) technology. If your audio recording contains more than one language, you can now enable multi-language identification, which identifies all languages spoken in the audio file and creates a transcript using each identified language. Automatic language identification for multilingual audio is supported for all 37 languages that are currently supported for batch transcriptions. Read the What’s New post from Amazon Transcribe to learn more.

Amazon Braket adds support for Borealis, the first publicly accessible quantum computer that is claimed to offer quantum advantage – If you are interested in quantum computing, you’ve likely heard the term “quantum advantage.” It refers to the technical milestone when a quantum computer outperforms the world’s fastest supercomputers on a well-defined task. Until now, none of the devices claimed to demonstrate quantum advantage have been accessible to the public. The Borealis device, a new photonic quantum processing unit (QPU) from Xanadu, is the first publicly available quantum computer that is claimed to have achieved quantum advantage. Amazon Braket, the quantum computing service from AWS, has just added support for Borealis. To learn more about how you can test a quantum advantage claim for yourself now on Amazon Braket, check out the What’s New post covering the addition of Borealis support.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Some other updates and news that you may have missed:

New AWS Heroes – A warm welcome to our newest AWS Heroes! The AWS Heroes program is a worldwide initiative that acknowledges individuals who have truly gone above and beyond to share knowledge in technical communities. Get to know them in the June 2022 introduction blog post!

AWS open-source news and updates – My colleague Ricardo Sueiras writes this weekly open-source newsletter in which he highlights new open-source projects, tools, and demos from the AWS Community. Read edition #115 here.

Upcoming AWS Events
Join me in Las Vegas for Amazon re:MARS 2022. The conference takes place June 21–24 and is all about the latest innovations in machine learning, automation, robotics, and space. I will deliver a talk on how machine learning can help to improve disaster response. Say “Hi!” if you happen to be around and see me.

We also have more AWS Summits coming up over the next couple of months, both in-person and virtual.

In Europe:

In North America:

In South America:

Find an AWS Summit near you, and get notified when registration opens in your area.

Imagine Conference 2022You can now register for IMAGINE 2022 (August 3, Seattle). The IMAGINE 2022 conference is a no-cost event that brings together education, state, and local leaders to learn about the latest innovations and best practices in the cloud.

Sign up for the SQL Server Database Modernization webinar on June 21 to learn how to modernize and cost-optimize Microsoft SQL Server on AWS.

That’s all for this week. Check back next Monday for another Week in Review!

— Antje