Tag Archives: Uncategorized

Pairwise Authentication of Humans

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/02/pairwise-authentication-of-humans.html

Here’s an easy system for two humans to remotely authenticate to each other, so they can be sure that neither are digital impersonations.

To mitigate that risk, I have developed this simple solution where you can setup a unique time-based one-time passcode (TOTP) between any pair of persons.

This is how it works:

  1. Two people, Person A and Person B, sit in front of the same computer and open this page;
  2. They input their respective names (e.g. Alice and Bob) onto the same page, and click “Generate”;
  3. The page will generate two TOTP QR codes, one for Alice and one for Bob;
  4. Alice and Bob scan the respective QR code into a TOTP mobile app (such as Authy or Google Authenticator) on their respective mobile phones;
  5. In the future, when Alice speaks with Bob over the phone or over video call, and wants to verify the identity of Bob, Alice asks Bob to provide the 6-digit TOTP code from the mobile app. If the code matches what Alice has on her own phone, then Alice has more confidence that she is speaking with the real Bob.

Simple, and clever.

UK Is Ordering Apple to Break Its Own Encryption

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/02/uk-is-ordering-apple-to-break-its-own-encryption.html

The Washington Post is reporting that the UK government has served Apple with a “technical capability notice” as defined by the 2016 Investigatory Powers Act, requiring it to break the Advanced Data Protection encryption in iCloud for the benefit of law enforcement.

This is a big deal, and something we in the security community have worried was coming for a while now.

The law, known by critics as the Snoopers’ Charter, makes it a criminal offense to reveal that the government has even made such a demand. An Apple spokesman declined to comment.

Apple can appeal the U.K. capability notice to a secret technical panel, which would consider arguments about the expense of the requirement, and to a judge who would weigh whether the request was in proportion to the government’s needs. But the law does not permit Apple to delay complying during an appeal.

In March, when the company was on notice that such a requirement might be coming, it told Parliament: “There is no reason why the U.K. [government] should have the authority to decide for citizens of the world whether they can avail themselves of the proven security benefits that flow from end-to-end encryption.”

Apple is likely to turn the feature off for UK users rather than break it for everyone worldwide. Of course, UK users will be able to spoof their location. But this might not be enough. According to the law, Apple would not be able to offer the feature to anyone who is in the UK at any point: for example, a visitor from the US.

And what happens next? Australia has a law enabling it to ask for the same thing. Will it? Will even more countries follow?

This is madness.

Introducing JSONL support with Step Functions Distributed Map

Post Syndicated from Eric Johnson original https://aws.amazon.com/blogs/compute/introducing-jsonl-support-with-step-functions-distributed-map/

This post written by Uma Ramadoss, Principal Specialist SA, Serverless and Vinita Shadangi, Senior Specialist SA, Serverless.

Today, AWS Step Functions is expanding the capabilities of Distributed Map by adding support for JSON Lines (JSONL) format. JSONL, a highly efficient text-based format, stores structured data as individual JSON objects separated by newlines, making it particularly suitable for processing large datasets.

This new capability enables you to process large collection of items stored in JSONL format directly through Distribtued Map and optionally exports the output of the Distributed Map as JSONL file. The enhancement also introduces support for additional delimited file formats, including semicolon and tab-delimited files, providing greater flexibility in data source options. Furthermore, new flexible output transformations gives developers more control over result formatting, enabling better integration with downstream processes for efficient data handling.

Overview

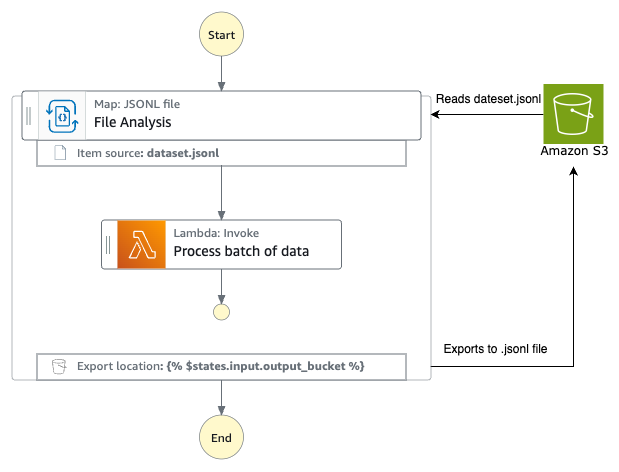
Distributed Map enables parallel processing of large-scale data by concurrently running the same processing steps for millions of entries in a dataset at the maximum scale of 10000. This is particularly useful for use cases like large scale payroll processing, image conversion, document processing and data migrations. Previously, the dataset can come from state input, JSON/CSV files in S3 and collection of S3 objects. With this new feature, the dataset can be a JSONL file in Amazon S3.

A diagram showing the AWSStep Functions workflow

The AWS Step Functions workflow

Consider an example of end-to-end GenAI batch inferencing using Amazon Bedrock. Batch inference helps you process a large number of requests efficiently by bundling them as single request and storing the results in an S3 bucket. Since both input and output are handled as JSONL files, the blog uses the scenario as an example to demonstrate the new capabilities of Distributed Map.

The diagram below shows the end-to-end flow –

  1. Step Functions workflow (Batch inference input generation worfklow) uses Distributed Map to build and bundle AI prompts for a collection of product review data. Workflow then invokes the Amazon Bedrock batch inference API.
  2. Amazon Bedrock stores the results in S3 as JSONL file when the batch inference is completed.
  3. An S3 object created event invokes the second Step Functions workflow (Batch inference output processing workflow) that processes the JSONL file and loads the results into an Amazon DynamoDB table.
Diagram showing the overall architecture for the end to end flow

Batch inferencing workflow

Introducing new output transformations through batch inference input generation workflow

The batch inference input generation workflow processes product review data in S3 using Distributed Map. Distributed Map spins multiple child workflows that generate AI prompts for sentiment analysis of each product review and exports the results of the child workflows to S3 as a JSONL file. The workflow calls Amazon Bedrock batch inference API (CreateModelInvocationJob) with the JSONL file as input upon completion of the Distributed Map state. Since the inference API operates asynchronously, the workflow completes immediately after receiving a successful response from the API.

Diagram of the AWS Step Function workflow that creates the batch process

Batch inference input generation workflow

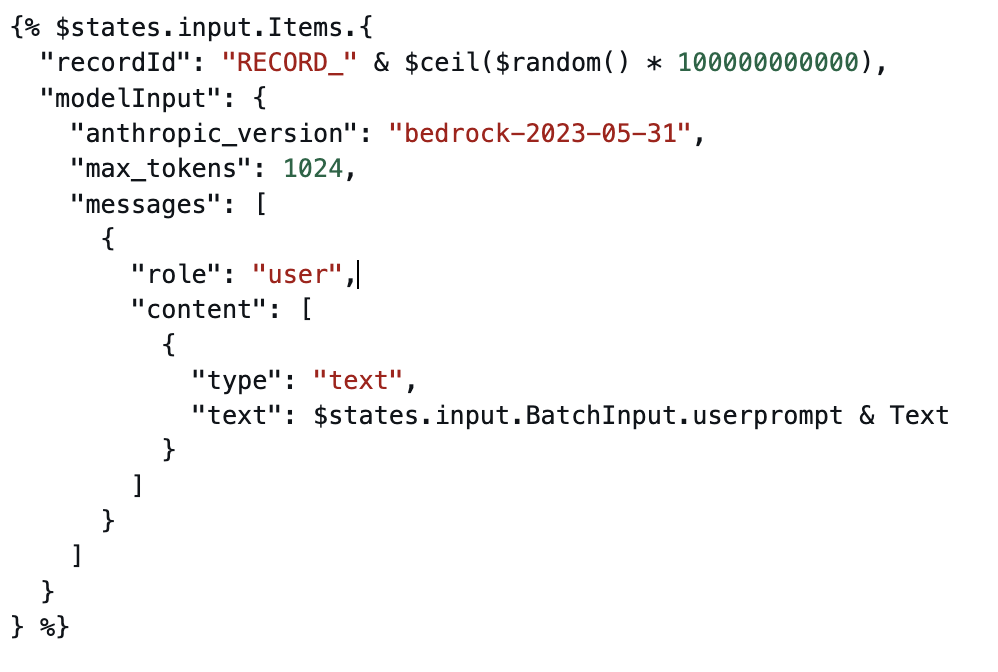
Each child workflow receives a batch of product reviews as an array. It operates on the array using Pass state to create an array of AI prompts, one for each item. The Pass state manipulates the input using JSONata expressions, generates unique recordId using JSONata numeric functions, and outputs the results in a format Amazon Bedrock expects.

JSONata transformation to generate prompts

JSONata transformation to generate prompts

Once all child workflows are complete, Distributed Map uses the new output transformations to export the outputs from child workflows to S3.

Using the new output transformations to export in JSONL format

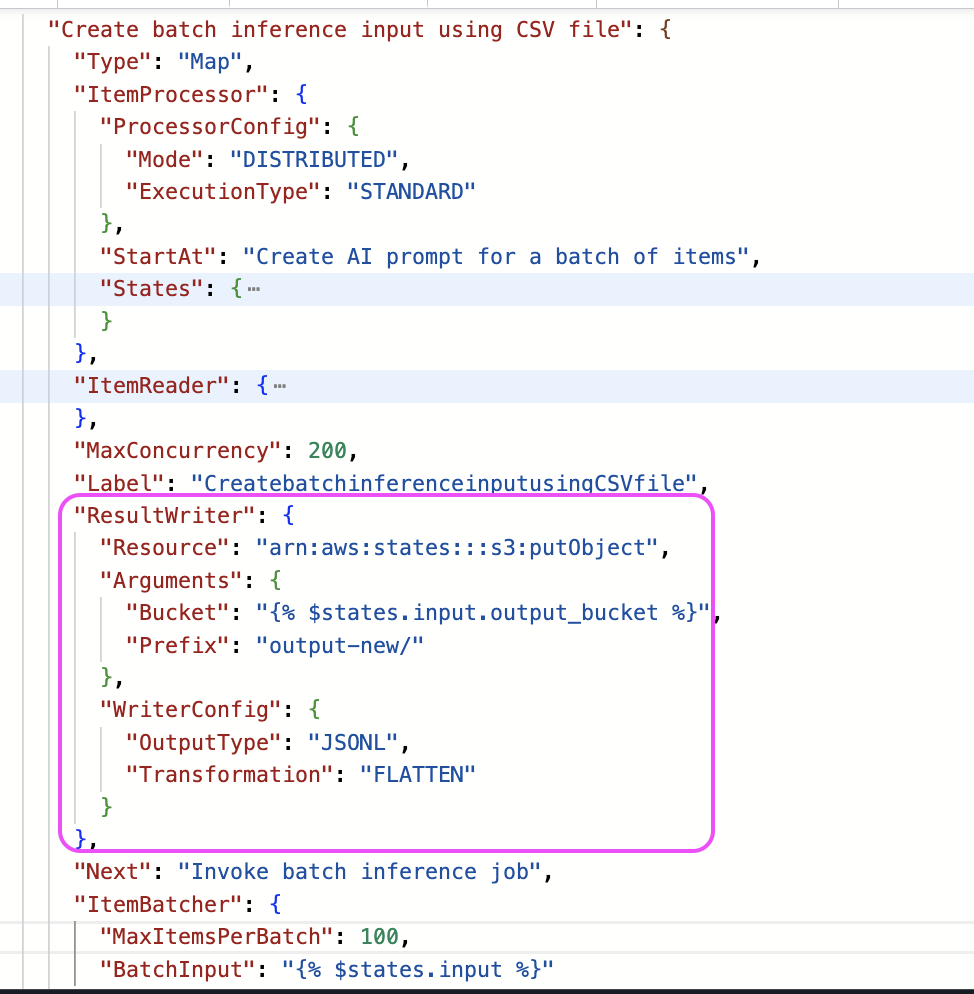
Distributed Map now offers more flexible output handling through an optional writer configuration. While it traditionally exports child workflow execution results to three separate JSON files (successful, failed, and pending), the new writer configuration streamlines the output and supports JSONL format in addition to JSON format.
The previous export option included comprehensive execution details – metadata, child workflow inputs, and outputs. The new configuration allows you to streamline output to include only the child workflow execution results, which are valuable for map/reduce patterns, where the output from one Distributed Map needs to feed directly into another without the need for additional transformation steps.

JSON structure showing the ASL for Step Functions

Output writer config for JSONL

Writer config also allows you to flatten the output array. When a child workflow processes batches of the input, it produces an array of results which will eventually become an array of arrays when the Distributed Map aggregates the outputs from all child workflows. With the new output transformation called FLATTEN, you can choose to flatten the array without additional code.

JSON examples showing the multiple arrays being flattened

Flattening output in JSONL

Introducing the new ItemReader for JSONL using batch inference output processing workflow

The second workflow processes output of the batch inference job by launching multiple child workflows using Distributed Map. Each child workflow processes batches of items, examining them for error objects and separating successful inferences from errors. The workflow then loads all successful inferences into a DynamoDB table while sending errors to a dead letter queue for subsequent analysis.

AWS Step Functions workflow architecture

Processing inference results

Using the new InputType to read the JSONL inference results

The Distributed Map in the batch inference results processing workflow uses the newly supported ItemReader-InputType, JSONL. Previously, the InputType only accepted CSV, JSON, and MANIFEST, which is an S3 Inventory manifest file.

AWS Step Functions ASL showing how to read the JSONL file

Reading JSONL file

There is no other change to how Distributed Map processes and shares data with child workflows. The Pass state in the child workflow receives batches of Items from the Map, and uses JSONata expressions to separate the errors from successful items.

AWS Step Functions ASL showing JSONata to separate processing for errors

Separating successful processing from errors

The following shows the input received by the Pass state and the output generated by the state using the above JSONata expression.

Resulting JSON showing processed records

Sample successful processing records

Using S3 events as connective tissue between the workflows

When Amazon Bedrock completes the batch inference job, it stores the output in the S3 location specified in the API request. An EventBridge rule triggers the batch inference results processing workflow using S3 event notifications. The rule looks for “Object Created” event from the specified S3 bucket and a wildcard pattern for JSONL file extension. When the rule matches the incoming event, it triggers the workflow.

JSON structure of an Amazon EventBridge rule

EventBridge rule

You can detect failed batch inference jobs by setting up EventBridge rules that listen to Amazon Bedrock status events. Since failed jobs don’t create output files in S3, monitoring status events directly ensures you catch and handle job failures.

Key considerations

  1. The new output transformations do not change the information in the FAILED execution results file in order to help you analyze the reasons for failures. To learn more about the output transformation configurations, visit the documentation.
  2. The new transformation mode FLATTEN, COMPACT stores only the output of the execution results. To inspect the results for fact checking or troubleshooting, use the default transformation.
  3. As a best practice, when implementing code changes, it’s advised to use the versioning and aliasing feature for gradual deployment of changes to production.
  4. When using Distributed Map, there is an option to configure the child workflow as either Standard or Express. Express is the recommended choice if each iteration (child workflow) can be completed within 5 minutes, and batching items will help optimize costs. To learn more about optimizations for Distributed Map, visit the workshop.

Conclusion

Step Functions Distributed Map is a powerful feature that enables developers to create large-scale data processing solutions with ease, eliminating concerns about operational aspects and software challenges like batching, concurrency, and failure handling. The addition of JSONL support for both input and output expands workload capabilities and minimizes additional effort through transformations by natively deserializing and flattening the output. This blog demonstrated the new feature’s capabilities through a practical example of building large-scale data processing applications using Distributed Map.

For more information on Distributed Map and how to use it with JSONL files, refer to the user guide.

To explore generative AI samples with Step Functions, visit the the GitiHub repo.

To expand your serverless knowledge, visit Serverless Land.

Screenshot-Reading Malware

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/02/screenshot-reading-malware.html

Kaspersky is reporting on a new type of smartphone malware.

The malware in question uses optical character recognition (OCR) to review a device’s photo library, seeking screenshots of recovery phrases for crypto wallets. Based on their assessment, infected Google Play apps have been downloaded more than 242,000 times. Kaspersky says: “This is the first known case of an app infected with OCR spyware being found in Apple’s official app marketplace.”

That’s a tactic I have not heard of before.

Introducing AWS CloudFormation Stack Refactoring

Post Syndicated from Kevin DeJong original https://aws.amazon.com/blogs/devops/introducing-aws-cloudformation-stack-refactoring/

Introduction

As your cloud infrastructure grows and evolves, you may find the need to reorganize your AWS CloudFormation stacks for better management, for improved modularity, or to align with changing business requirements. CloudFormation now offers a powerful feature that allows you to move resources between stacks. In this post, we’ll explore the process of stack refactoring and how it can help you maintain a well-organized and efficient cloud infrastructure.

Understanding Stack Refactoring

Stack refactoring is the process of restructuring your CloudFormation stacks by moving resources from one stack to another or renaming a resource with a new logical ID within the same stack. This capability is particularly useful when you want to:

  • Split a large, monolithic stack into smaller, more manageable stacks
  • Reorganize resources to better align with your application architecture or organizational structure
  • Rename the logical IDs of resources to make templates more readable

Example Scenario

To demonstrate this capability, you are going to create a stack and then move some of its resources into a new stack. You will evaluate the new CLI commands that you need to leverage to make this possible. For this example, you are going to have an SNS topic with a lambda function subscribed to your SNS topic. As your usage of the SNS topic expands, you want to break apart the subscriptions into a different stack.

  1. Create a new template called before.yaml with your starting template:
    AWSTemplateFormatVersion: "2010-09-09"
    
    Resources:
      Topic:
        Type: AWS::SNS::Topic
    
      MyFunction:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: my-function
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                  print(json.dumps(event))
                  return event
          Role: !GetAtt FunctionRole.Arn
          Timeout: 30
    
      Subscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt MyFunction.Arn
          Protocol: lambda
          TopicArn: !Ref Topic
    
      FunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt MyFunction.Arn
          SourceArn: !Ref Topic
    
      FunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                 Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub "arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:my-function"
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow
  2. Create a new stack using the before.yaml template.
    aws cloudformation create-stack --stack-name MySns --template-body file://before.yaml --capabilities CAPABILITY_IAM
    
  3. Create a new template called afterSns.yaml with the content below. This template has your SNS topic in it and has a new export in it that will export the SNS topic ARN. This export will be used by your other templates to get the required SNS topic ARN.
    AWSTemplateFormatVersion: "2010-09-09"
    Resources:
      Topic:
        Type: AWS::SNS::Topic
    Outputs:
      TopicArn:
        Value: !Ref Topic
        Export:
          Name: TopicArn
  4. Create a new template called afterLambda.yaml with the content below. This template includes all the resources to create a Lambda subscription to your SNS topic. This template switched the !Ref Topic to use the exported valued by using !ImportValue TopicArn.
    AWSTemplateFormatVersion: "2010-09-09"
    Resources:
      Function:
        Type: AWS::Lambda::Function
        Properties:
          FunctionName: my-function
          Handler: index.handler
          Runtime: python3.12
          Code:
            ZipFile: |
              import json
              def handler(event, context):
                print(json.dumps(event))
                return event
          Role: !GetAtt FunctionRole.Arn
          Timeout: 30
      Subscription:
        Type: AWS::SNS::Subscription
        Properties:
          Endpoint: !GetAtt Function.Arn
          Protocol: lambda
          TopicArn: !ImportValue TopicArn
      FunctionInvokePermission:
        Type: AWS::Lambda::Permission
        Properties:
          Action: lambda:InvokeFunction
          Principal: sns.amazonaws.com
          FunctionName: !GetAtt Function.Arn
          SourceArn: !ImportValue TopicArn
      FunctionRole:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: "2012-10-17"
            Statement:
              - Action:
                  - sts:AssumeRole
                Effect: Allow
                Principal:
                  Service:
                    - lambda.amazonaws.com
                 Condition:
                  StringEquals:
                    aws:SourceAccount: !Ref AWS::AccountId
                  ArnLike:
                    aws:SourceArn: !Sub arn:${AWS::Partition}:lambda:${AWS::Region}:${AWS::AccountId}:function:*
          Policies:
            - PolicyName: LambdaPolicy
              PolicyDocument:
                Version: "2012-10-17"
                Statement:
                  - Action:
                      - logs:CreateLogGroup
                      - logs:CreateLogStream
                      - logs:PutLogEvents
                    Resource:
                      - arn:aws:logs:*:*:*
                    Effect: Allow
    
  5. Create a resource mappings file called refactor.json to rename the logical ID of a resource. This file defines the source and destination stack names and logical IDs for resources being refactored. If the logical IDs don’t change, this file doesn’t need to be specified.
    [
        {
            "Source": {
                "StackName": "MySns",
                "LogicalResourceId": "MyFunction"
            },
            "Destination": {
                "StackName": "MyLambdaSubscription",
                "LogicalResourceId": "Function"
            }
        }
    ]
    
  6. Create a stack refactor task. You are using enable-stack-creation to tell the refactoring capability to create the destination stack for us. If the destination stack already exists you don’t have to provide this option.
    aws cloudformation create-stack-refactor --stack-definitions StackName=MySns,TemplateBody@=file://afterSns.yaml StackName=MyLambdaSubscription,TemplateBody@=file://afterLambda.yaml --enable-stack-creation --resource-mappings file://refactor.json
    

    Results:

    {
        "StackRefactorId": "56b06a9a-72ff-4f87-8205-32111bff83f9"
    }
    

    Capture the stack refactor ID for the following steps.

  7. Evaluate the stack refactor task.
    aws cloudformation describe-stack-refactor --stack-refactor-id 56b06a9a-72ff-4f87-8205-32111bff83f9
    

    results:

    {
        "StackRefactorId": "56b06a9a-72ff-4f87-8205-32111bff83f9",
        "StackIds": [
            "arn:aws:cloudformation:<<AWS::Region>>:<<AWS::AccountId>>:stack/MySns/a10bfd30-cc67-11ef-877a-023cc5780193",
            "arn:aws:cloudformation:<<AWS::Region>>:<<AWS::AccountId>>:stack/MyLambdaSubscription/6d117360-cc68-11ef-ba33-06338dcc9d39"
        ],
        "ExecutionStatus": "AVAILABLE",
        "Status": "CREATE_COMPLETE"
    }
    

    If you forgot to capture the stack refactor ID you can run:

    aws cloudformation list-stack-refactors
    

    You can list stack the actions that the refactor did by running:

    aws cloudformation list-stack-refactor-actions —stack-refactor-id 56b06a9a-72ff-4f87-8205-32111bff83f9
    

    You will see that the refactor will create a new stack and what resources are being moved.

    {
        "StackRefactorActions": [
            {
                "Action": "Move",
                "Entity": "Resource",
                "PhysicalResourceId": "MySns-FunctionRole-BMO7ohLu4S6a",
                "Description": "No configuration changes detected.",
                "Detection": "Auto",
                "TagResources": [],
                "UntagResources": [],
                "ResourceMapping": {
                    "Source": {
                        "StackName": "arn:aws:cloudformation:<<AWS::Region>>:<<AWS::AccountId>>:stack/MySns/a10bfd30-cc67-11ef-877a-023cc5780193",
                        "LogicalResourceId": "FunctionRole"
                    },
                    "Destination": {
                        "StackName": "arn:aws:cloudformation:<<AWS::Region>>:<<AWS::AccountId>>:stack/MyLambdaSubscription/6d117360-cc68-11ef-ba33-06338dcc9d39",
                        "LogicalResourceId": "FunctionRole"
                    }
                }
            },
            {
                "Action": "Create",
                "Entity": "Stack",
                "Description": "Stack arn:aws:cloudformation:<<AWS::Region>>:<<AWS::AccountId>>:stack/MyLambdaSubscription/6d117360-cc68-11ef-ba33-06338dcc9d39 created.",
                "Detection": "Manual",
                "TagResources": [],
                "UntagResources": [],
                "ResourceMapping": {
                    "Source": {},
                    "Destination": {}
                }
            },
    ...
    
  8. Execute the stack refactor
    aws cloudformation execute-stack-refactor --stack-refactor-id 56b06a9a-72ff-4f87-8205-32111bff83f9
    
  9. Wait for the stack refactor to complete. Evaluate the stack refactor status by executing:
    aws cloudformation describe-stack-refactor --stack-refactor-id 56b06a9a-72ff-4f87-8205-32111bff83f9
    
    {
        "StackRefactorId": "56b06a9a-72ff-4f87-8205-32111bff83f9",
        "StackIds": [
            "arn:aws:cloudformation:<<AWS::Region>>:<<AWS::AccountId>>:stack/MySns/a10bfd30-cc67-11ef-877a-023cc5780193",
            "arn:aws:cloudformation:<<AWS::Region>>:<<AWS::AccountId>>:stack/MyLambdaSubscription/6d117360-cc68-11ef-ba33-06338dcc9d39"
        ],
        "ExecutionStatus": "EXECUTE_COMPLETE",
        "Status": "CREATE_COMPLETE"
    }
    

Conclusion

Stack refactoring in AWS CloudFormation represents a significant advancement in infrastructure management, offering a safer and more efficient way to reorganize your cloud resources without disruption. This feature eliminates the traditional need to remove the resource, with a retain policy, and then import the resource when restructuring stacks, helping you reduce misconfiguration risk and save time. Through the example demonstrated in this post, you’ve seen how to split a monolithic stack into smaller, focused stacks while using exports and imports to maintain dependencies between stacks. You’ve also explored the new CloudFormation CLI commands that make stack refactoring possible while maintaining resource stability during reorganization.

As your infrastructure evolves, stack refactoring provides the flexibility needed to adapt your CloudFormation stack organization to changing requirements while maintaining the integrity of your cloud resources. This capability is particularly valuable for teams looking to improve their infrastructure maintainability and align their resource organization with evolving architectural patterns. Remember to thoroughly test your refactoring plans in a non-production environment first, and always ensure your new stack structure maintains the necessary security and access controls.

Kevin DeJong

Kevin DeJong is a Software Development Engineer – Infrastructure as Code at AWS. He is creator and maintainer of cfn-lint. Kevin has been working with the CloudFormation service for over 10 years.

AIs and Robots Should Sound Robotic

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/02/ais-and-robots-should-sound-robotic.html

Most people know that robots no longer sound like tinny trash cans. They sound like Siri, Alexa, and Gemini. They sound like the voices in labyrinthine customer support phone trees. And even those robot voices are being made obsolete by new AI-generated voices that can mimic every vocal nuance and tic of human speech, down to specific regional accents. And with just a few seconds of audio, AI can now clone someone’s specific voice.

This technology will replace humans in many areas. Automated customer support will save money by cutting staffing at call centers. AI agents will make calls on our behalf, conversing with others in natural language. All of that is happening, and will be commonplace soon.

But there is something fundamentally different about talking with a bot as opposed to a person. A person can be a friend. An AI cannot be a friend, despite how people might treat it or react to it. AI is at best a tool, and at worst a means of manipulation. Humans need to know whether we’re talking with a living, breathing person or a robot with an agenda set by the person who controls it. That’s why robots should sound like robots.

You can’t just label AI-generated speech. It will come in many different forms. So we need a way to recognize AI that works no matter the modality. It needs to work for long or short snippets of audio, even just a second long. It needs to work for any language, and in any cultural context. At the same time, we shouldn’t constrain the underlying system’s sophistication or language complexity.

We have a simple proposal: all talking AIs and robots should use a ring modulator. In the mid-twentieth century, before it was easy to create actual robotic-sounding speech synthetically, ring modulators were used to make actors’ voices sound robotic. Over the last few decades, we have become accustomed to robotic voices, simply because text-to-speech systems were good enough to produce intelligible speech that was not human-like in its sound. Now we can use that same technology to make robotic speech that is indistinguishable from human sound robotic again.

A ring modulator has several advantages: It is computationally simple, can be applied in real-time, does not affect the intelligibility of the voice, and—most importantly—is universally “robotic sounding” because of its historical usage for depicting robots.

Responsible AI companies that provide voice synthesis or AI voice assistants in any form should add a ring modulator of some standard frequency (say, between 30-80 Hz) and of a minimum amplitude (say, 20 percent). That’s it. People will catch on quickly.

Here are a couple of examples you can listen to for examples of what we’re suggesting. The first clip is an AI-generated “podcast” of this article made by Google’s NotebookLM featuring two AI “hosts.” Google’s NotebookLM created the podcast script and audio given only the text of this article. The next two clips feature that same podcast with the AIs’ voices modulated more and less subtly by a ring modulator:

Raw audio sample generated by Google’s NotebookLM

Audio sample with added ring modulator (30 Hz-25%)

Audio sample with added ring modulator (30 Hz-40%)

We were able to generate the audio effect with a 50-line Python script generated by Anthropic’s Claude. One of the most well-known robot voices were those of the Daleks from Doctor Who in the 1960s. Back then robot voices were difficult to synthesize, so the audio was actually an actor’s voice run through a ring modulator. It was set to around 30 Hz, as we did in our example, with different modulation depth (amplitude) depending on how strong the robotic effect is meant to be. Our expectation is that the AI industry will test and converge on a good balance of such parameters and settings, and will use better tools than a 50-line Python script, but this highlights how simple it is to achieve.

Of course there will also be nefarious uses of AI voices. Scams that use voice cloning have been getting easier every year, but they’ve been possible for many years with the right know-how. Just like we’re learning that we can no longer trust images and videos we see because they could easily have been AI-generated, we will all soon learn that someone who sounds like a family member urgently requesting money may just be a scammer using a voice-cloning tool.

We don’t expect scammers to follow our proposal: They’ll find a way no matter what. But that’s always true of security standards, and a rising tide lifts all boats. We think the bulk of the uses will be with popular voice APIs from major companies—and everyone should know that they’re talking with a robot.

This essay was written with Barath Raghavan, and originally appeared in IEEE Spectrum.

On Generative AI Security

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/02/on-generative-ai-security.html

Microsoft’s AI Red Team just published “Lessons from Red Teaming 100 Generative AI Products.” Their blog post lists “three takeaways,” but the eight lessons in the report itself are more useful:

  1. Understand what the system can do and where it is applied.
  2. You don’t have to compute gradients to break an AI system.
  3. AI red teaming is not safety benchmarking.
  4. Automation can help cover more of the risk landscape.
  5. The human element of AI red teaming is crucial.
  6. Responsible AI harms are pervasive but difficult to measure.
  7. LLMs amplify existing security risks and introduce new ones.
  8. The work of securing AI systems will never be complete.

Deepfakes and the 2024 US Election

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/02/deepfakes-and-the-2024-us-election.html

Interesting analysis:

We analyzed every instance of AI use in elections collected by the WIRED AI Elections Project (source for our analysis), which tracked known uses of AI for creating political content during elections taking place in 2024 worldwide. In each case, we identified what AI was used for and estimated the cost of creating similar content without AI.

We find that (1) half of AI use isn’t deceptive, (2) deceptive content produced using AI is nevertheless cheap to replicate without AI, and (3) focusing on the demand for misinformation rather than the supply is a much more effective way to diagnose problems and identify interventions.

This tracks with my analysis. People share as a form of social signaling. I send you a meme/article/clipping/photo to show that we are on the same team. Whether it is true, or misinformation, or actual propaganda, is of secondary importance. Sometimes it’s completely irrelevant. This is why fact checking doesn’t work. This is why “cheap fakes”—obviously fake photos and videos—are effective. This is why, as the authors of that analysis said, the demand side is the real problem.

Journalists and Civil Society Members Using WhatsApp Targeted by Paragon Spyware

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/02/journalists-and-civil-society-members-using-whatsapp-targeted-by-paragon-spyware.html

This is yet another story of commercial spyware being used against journalists and civil society members.

The journalists and other civil society members were being alerted of a possible breach of their devices, with WhatsApp telling the Guardian it had “high confidence” that the 90 users in question had been targeted and “possibly compromised.”

It is not clear who was behind the attack. Like other spyware makers, Paragon’s hacking software is used by government clients and WhatsApp said it had not been able to identify the clients who ordered the alleged attacks.

Experts said the targeting was a “zero-click” attack, which means targets would not have had to click on any malicious links to be infected.

Fake Reddit and WeTransfer Sites are Pushing Malware

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/01/fake-reddit-and-wetransfer-sites-are-pushing-malware.html

There are thousands of fake Reddit and WeTransfer webpages that are pushing malware. They exploit people who are using search engines to search sites like Reddit.

Unsuspecting victims clicking on the link are taken to a fake WeTransfer site that mimicks the interface of the popular file-sharing service. The ‘Download’ button leads to the Lumma Stealer payload hosted on “weighcobbweo[.]top.”

Boingboing post.

ExxonMobil Lobbyist Caught Hacking Climate Activists

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/01/exxonmobil-lobbyist-caught-hacking-climate-activists.html

The Department of Justice is investigating a lobbying firm representing ExxonMobil for hacking the phones of climate activists:

The hacking was allegedly commissioned by a Washington, D.C., lobbying firm, according to a lawyer representing the U.S. government. The firm, in turn, was allegedly working on behalf of one of the world’s largest oil and gas companies, based in Texas, that wanted to discredit groups and individuals involved in climate litigation, according to the lawyer for the U.S. government. In court documents, the Justice Department does not name either company.

As part of its probe, the U.S. is trying to extradite an Israeli private investigator named Amit Forlit from the United Kingdom for allegedly orchestrating the hacking campaign. A lawyer for Forlit claimed in a court filing that the hacking operation her client is accused of leading “is alleged to have been commissioned by DCI Group, a lobbying firm representing ExxonMobil, one of the world’s largest fossil fuel companies.”

CISA Under Trump

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/01/cisa-under-trump.html

Jen Easterly is out as the Director of CISA. Read her final interview:

There’s a lot of unfinished business. We have made an impact through our ransomware vulnerability warning pilot and our pre-ransomware notification initiative, and I’m really proud of that, because we work on preventing somebody from having their worst day. But ransomware is still a problem. We have been laser-focused on PRC cyber actors. That will continue to be a huge problem. I’m really proud of where we are, but there’s much, much more work to be done. There are things that I think we can continue driving, that the next administration, I hope, will look at, because, frankly, cybersecurity is a national security issue.

If Project 2025 is a guide, the agency will be gutted under Trump:

“Project 2025’s recommendations—essentially because this one thing caused anger—is to just strip the agency of all of its support altogether,” he said. “And CISA’s functions go so far beyond its role in the information space in a way that would do real harm to election officials and leave them less prepared to tackle future challenges.”

In the DHS chapter of Project 2025, Cucinelli suggests gutting CISA almost entirely, moving its core responsibilities on critical infrastructure to the Department of Transportation. It’s a suggestion that Adav Noti, the executive director of the nonpartisan voting rights advocacy organization Campaign Legal Center, previously described to Democracy Docket as “absolutely bonkers.”

“It’s located at Homeland Security because the whole premise of the Department of Homeland Security is that it’s supposed to be the central resource for the protection of the nation,” Noti said. “And that the important functions shouldn’t be living out in siloed agencies.”

New VPN Backdoor

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/01/new-vpn-backdoor.html

A newly discovered VPN backdoor uses some interesting tactics to avoid detection:

When threat actors use backdoor malware to gain access to a network, they want to make sure all their hard work can’t be leveraged by competing groups or detected by defenders. One countermeasure is to equip the backdoor with a passive agent that remains dormant until it receives what’s known in the business as a “magic packet.” On Thursday, researchers revealed that a never-before-seen backdoor that quietly took hold of dozens of enterprise VPNs running Juniper Network’s Junos OS has been doing just that.

J-Magic, the tracking name for the backdoor, goes one step further to prevent unauthorized access. After receiving a magic packet hidden in the normal flow of TCP traffic, it relays a challenge to the device that sent it. The challenge comes in the form of a string of text that’s encrypted using the public portion of an RSA key. The initiating party must then respond with the corresponding plaintext, proving it has access to the secret key.

The lightweight backdoor is also notable because it resided only in memory, a trait that makes detection harder for defenders. The combination prompted researchers at Lumin Technology’s Black Lotus Lab to sit up and take notice.

[…]

The researchers found J-Magic on VirusTotal and determined that it had run inside the networks of 36 organizations. They still don’t know how the backdoor got installed.

Slashdot thread.

EDITED TO ADD (2/1): Another article.

Friday Squid Blogging: Beaked Whales Feed on Squid

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/01/friday-squid-blogging-beaked-whales-feed-on-squid.html

A Travers’ beaked whale (Mesoplodon traversii) washed ashore in New Zealand, and scientists conlcuded that “the prevalence of squid remains [in its stomachs] suggests that these deep-sea cephalopods form a significant part of the whale’s diet, similar to other beaked whale species.”

Blog moderation policy.

Third Interdisciplinary Workshop on Reimagining Democracy (IWORD 2024)

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/01/third-interdisciplinary-workshop-on-reimagining-democracy-iword-2024.html

Last month, Henry Farrell and I convened the Third Interdisciplinary Workshop on Reimagining Democracy (IWORD 2024) at Johns Hopkins University’s Bloomberg Center in Washington DC. This is a small, invitational workshop on the future of democracy. As with the previous two workshops, the goal was to bring together a diverse set of political scientists, law professors, philosophers, AI researchers and other industry practitioners, political activists, and creative types (including science fiction writers) to discuss how democracy might be reimagined in the current century.

The goal of the workshop is to think very broadly. Modern democracy was invented in the mid-eighteenth century, using mid-eighteenth-century technology. If democracy were to be invented today, it would look very different. Elections would look different. The balance between representation and direct democracy would look different. Adjudication and enforcement would look different. Everything would look different, because our conceptions of fairness, justice, equality, and rights are different, and we have much more powerful technology to bring to bear on the problems. Also, we could start from scratch without having to worry about evolving our current democracy into this imagined future system.

We can’t do that, of course, but it’s still still valuable to speculate. Of course we need to figure out how to reform our current systems, but we shouldn’t limit our thinking to incremental steps. We also need to think about discontinuous changes as well. I wrote about the philosophy more in this essay about IWORD 2022.

IWORD 2024 was easily the most intellectually stimulating two days of my year. It’s also intellectually exhausting; the speed and intensity of ideas is almost too much. I wrote the format in my blog post on IWORD 2023.

Summaries of all the IWORD 2024 talks are in the first set of comments below. And here are links to the previous IWORDs:

IWORD 2025 will be held either in New York or New Haven; still to be determined.

AI Will Write Complex Laws

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/01/ai-will-write-complex-laws.html

Artificial intelligence (AI) is writing law today. This has required no changes in legislative procedure or the rules of legislative bodies—all it takes is one legislator, or legislative assistant, to use generative AI in the process of drafting a bill.

In fact, the use of AI by legislators is only likely to become more prevalent. There are currently projects in the US House, US Senate, and legislatures around the world to trial the use of AI in various ways: searching databases, drafting text, summarizing meetings, performing policy research and analysis, and more. A Brazilian municipality passed the first known AI-written law in 2023.

That’s not surprising; AI is being used more everywhere. What is coming into focus is how policymakers will use AI and, critically, how this use will change the balance of power between the legislative and executive branches of government. Soon, US legislators may turn to AI to help them keep pace with the increasing complexity of their lawmaking—and this will suppress the power and discretion of the executive branch to make policy.

Demand for Increasingly Complex Legislation

Legislators are writing increasingly long, intricate, and complicated laws that human legislative drafters have trouble producing. Already in the US, the multibillion-dollar lobbying industry is subsidizing lawmakers in writing baroque laws: suggesting paragraphs to add to bills, specifying benefits for some, carving out exceptions for others. Indeed, the lobbying industry is growing in complexity and influence worldwide.

Several years ago, researchers studied bills introduced into state legislatures throughout the US, looking at which bills were wholly original texts and which borrowed text from other states or from lobbyist-written model legislation. Their conclusion was not very surprising. Those who borrowed the most text were in legislatures that were less resourced. This makes sense: If you’re a part-time legislator, perhaps unpaid and without a lot of staff, you need to rely on more external support to draft legislation. When the scope of policymaking outstrips the resources of legislators, they look for help. Today, that often means lobbyists, who provide expertise, research services, and drafting labor to legislators at the local, state, and federal levels at no charge. Of course, they are not unbiased: They seek to exert influence on behalf of their clients.

Another study, at the US federal level, measured the complexity of policies proposed in legislation and tried to determine the factors that led to such growing complexity. While there are numerous ways to measure legal complexity, these authors focused on the specificity of institutional design: How exacting is Congress in laying out the relational network of branches, agencies, and officials that will share power to implement the policy?

In looking at bills enacted between 1993 and 2014, the researchers found two things. First, they concluded that ideological polarization drives complexity. The suggestion is that if a legislator is on the extreme end of the ideological spectrum, they’re more likely to introduce a complex law that constrains the discretion of, as the authors put it, “entrenched bureaucratic interests.” And second, they found that divided government drives complexity to a large degree: Significant legislation passed under divided government was found to be 65 percent more complex than similar legislation passed under unified government. Their conclusion is that, if a legislator’s party controls Congress, and the opposing party controls the White House, the legislator will want to give the executive as little wiggle room as possible. When legislators’ preferences disagree with the executive’s, the legislature is incentivized to write laws that specify all the details. This gives the agency designated to implement the law as little discretion as possible.

Because polarization and divided government are increasingly entrenched in the US, the demand for complex legislation at the federal level is likely to grow. Today, we have both the greatest ideological polarization in Congress in living memory and an increasingly divided government at the federal level. Between 1900 and 1970 (57th through 90th Congresses), we had 27 instances of unified government and only seven divided; nearly a four-to-one ratio. Since then, the trend is roughly the opposite. As of the start of the next Congress, we will have had 20 divided governments and only eight unified (nearly a three-to-one ratio). And while the incoming Trump administration will see a unified government, the extremely closely divided House may often make this Congress look and feel like a divided one (see the recent government shutdown crisis as an exemplar) and makes truly divided government a strong possibility in 2027.

Another related factor driving the complexity of legislation is the need to do it all at once. The lobbyist feeding frenzy—spurring major bills like the Affordable Care Act to be thousands of pages in length—is driven in part by gridlock in Congress. Congressional productivity has dropped so low that bills on any given policy issue seem like a once-in-a-generation opportunity for legislators—and lobbyists—to set policy.

These dynamics also impact the states. States often have divided governments, albeit less often than they used to, and their demand for drafting assistance is arguably higher due to their significantly smaller staffs. And since the productivity of Congress has cratered in recent years, significantly more policymaking is happening at the state level.

But there’s another reason, particular to the US federal government, that will likely force congressional legislation to be more complex even during unified government. In June 2024, the US Supreme Court overturned the Chevron doctrine, which gave executive agencies broad power to specify and implement legislation. Suddenly, there is a mandate from the Supreme Court for more specific legislation. Issues that have historically been left implicitly to the executive branch are now required to be either explicitly delegated to agencies or specified directly in statute. Either way, the Court’s ruling implied that law should become more complex and that Congress should increase its policymaking capacity.

This affects the balance of power between the executive and legislative branches of government. When the legislature delegates less to the executive branch, it increases its own power. Every decision made explicitly in statute is a decision the executive makes not on its own but, rather, according to the directive of the legislature. In the US system of separation of powers, administrative law is a tool for balancing power among the legislative, executive, and judicial branches. The legislature gets to decide when to delegate and when not to, and it can respond to judicial review to adjust its delegation of control as needed. The elimination of Chevron will induce the legislature to exert its control over delegation more robustly.

At the same time, there are powerful political incentives for Congress to be vague and to rely on someone else, like agency bureaucrats, to make hard decisions. That empowers third parties—the corporations, or lobbyists—that have been gifted by the overturning of Chevron a new tool in arguing against administrative regulations not specifically backed up by law. A continuing stream of Supreme Court decisions handing victories to unpopular industries could be another driver of complex law, adding political pressure to pass legislative fixes.

AI Can Supply Complex Legislation

Congress may or may not be up to the challenge of putting more policy details into law, but the external forces outlined above—lobbyists, the judiciary, and an increasingly divided and polarized government—are pushing them to do so. When Congress does take on the task of writing complex legislation, it’s quite likely it will turn to AI for help.

Two particular AI capabilities enable Congress to write laws different from laws humans tend to write. One, AI models have an enormous scope of expertise, whereas people have only a handful of specializations. Large language models (LLMs) like the one powering ChatGPT can generate legislative text on funding specialty crop harvesting mechanization equally as well as material on energy efficiency standards for street lighting. This enables a legislator to address more topics simultaneously. Two, AI models have the sophistication to work with a higher degree of complexity than people can. Modern LLM systems can instantaneously perform several simultaneous multistep reasoning tasks using information from thousands of pages of documents. This enables a legislator to fill in more baroque detail on any given topic.

That’s not to say that handing over legislative drafting to machines is easily done. Modernizing any institutional process is extremely hard, even when the technology is readily available and performant. And modern AI still has a ways to go to achieve mastery of complex legal and policy issues. But the basic tools are there.

AI can be used in each step of lawmaking, and this will bring various benefits to policymakers. It could let them work on more policies—more bills—at the same time, add more detail and specificity to each bill, or interpret and incorporate more feedback from constituents and outside groups. The addition of a single AI tool to a legislative office may have an impact similar to adding several people to their staff, but with far lower cost.

Speed sometimes matters when writing law. When there is a change of governing party, there is often a rush to change as much policy as possible to match the platform of the new regime. AI could help legislators do that kind of wholesale revision. The result could be policy that is more responsive to voters—or more political instability. Already in 2024, the US House’s Office of the Clerk has begun using AI to speed up the process of producing cost estimates for bills and understanding how new legislation relates to existing code. Ohio has used an AI tool to do wholesale revision of state administrative law since 2020.

AI can also make laws clearer and more consistent. With their superhuman attention spans, AI tools are good at enforcing syntactic and grammatical rules. They will be effective at drafting text in precise and proper legislative language, or offering detailed feedback to human drafters. Borrowing ideas from software development, where coders use tools to identify common instances of bad programming practices, an AI reviewer can highlight bad law-writing practices. For example, it can detect when significant phrasing is inconsistent across a long bill. If a bill about insurance repeatedly lists a variety of disaster categories, but leaves one out one time, AI can catch that.

Perhaps this seems like minutiae, but a small ambiguity or mistake in law can have massive consequences. In 2015, the Affordable Care Act came close to being struck down because of a typo in four words, imperiling health care services extended to more than 7 million Americans.

There’s more that AI can do in the legislative process. AI can summarize bills and answer questions about their provisions. It can highlight aspects of a bill that align with, or are contrary to, different political points of view. We can even imagine a future in which AI can be used to simulate a new law and determine whether or not it would be effective, or what the side effects would be. This means that beyond writing them, AI could help lawmakers understand laws. Congress is notorious for producing bills hundreds of pages long, and many other countries sometimes have similarly massive omnibus bills that address many issues at once. It’s impossible for any one person to understand how each of these bills’ provisions would work. Many legislatures employ human analysis in budget or fiscal offices that analyze these bills and offer reports. AI could do this kind of work at greater speed and scale, so legislators could easily query an AI tool about how a particular bill would affect their district or areas of concern.

This is a use case that the House subcommittee on modernization has urged the Library of Congress to take action on. Numerous software vendors are already marketing AI legislative analysis tools. These tools can potentially find loopholes or, like the human lobbyists of today, craft them to benefit particular private interests.

These capabilities will be attractive to legislators who are looking to expand their power and capabilities but don’t necessarily have more funding to hire human staff. We should understand the idea of AI-augmented lawmaking contextualized within the longer history of legislative technologies. To serve society at modern scales, we’ve had to come a long way from the Athenian ideals of direct democracy and sortition. Democracy no longer involves just one person and one vote to decide a policy. It involves hundreds of thousands of constituents electing one representative, who is augmented by a staff as well as subsidized by lobbyists, and who implements policy through a vast administrative state coordinated by digital technologies. Using AI to help those representatives specify and refine their policy ideas is part of a long history of transformation.

Whether all this AI augmentation is good for all of us subject to the laws they make is less clear. There are real risks to AI-written law, but those risks are not dramatically different from what we endure today. AI-written law trying to optimize for certain policy outcomes may get it wrong (just as many human-written laws are misguided). AI-written law may be manipulated to benefit one constituency over others, by the tech companies that develop the AI, or by the legislators who apply it, just as human lobbyists steer policy to benefit their clients.

Regardless of what anyone thinks of any of this, regardless of whether it will be a net positive or a net negative, AI-made legislation is coming—the growing complexity of policy demands it. It doesn’t require any changes in legislative procedures or agreement from any rules committee. All it takes is for one legislative assistant, or lobbyist, to fire up a chatbot and ask it to create a draft. When legislators voted on that Brazilian bill in 2023, they didn’t know it was AI-written; the use of ChatGPT was undisclosed. And even if they had known, it’s not clear it would have made a difference. In the future, as in the past, we won’t always know which laws will have good impacts and which will have bad effects, regardless of the words on the page, or who (or what) wrote them.

This essay was written with Nathan E. Sanders, and originally appeared in Lawfare.

AI Mistakes Are Very Different from Human Mistakes

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/01/ai-mistakes-are-very-different-from-human-mistakes.html

Humans make mistakes all the time. All of us do, every day, in tasks both new and routine. Some of our mistakes are minor and some are catastrophic. Mistakes can break trust with our friends, lose the confidence of our bosses, and sometimes be the difference between life and death.

Over the millennia, we have created security systems to deal with the sorts of mistakes humans commonly make. These days, casinos rotate their dealers regularly, because they make mistakes if they do the same task for too long. Hospital personnel write on limbs before surgery so that doctors operate on the correct body part, and they count surgical instruments to make sure none were left inside the body. From copyediting to double-entry bookkeeping to appellate courts, we humans have gotten really good at correcting human mistakes.

Humanity is now rapidly integrating a wholly different kind of mistake-maker into society: AI. Technologies like large language models (LLMs) can perform many cognitive tasks traditionally fulfilled by humans, but they make plenty of mistakes. It seems ridiculous when chatbots tell you to eat rocks or add glue to pizza. But it’s not the frequency or severity of AI systems’ mistakes that differentiates them from human mistakes. It’s their weirdness. AI systems do not make mistakes in the same ways that humans do.

Much of the friction—and risk—associated with our use of AI arise from that difference. We need to invent new security systems that adapt to these differences and prevent harm from AI mistakes.

Human Mistakes vs AI Mistakes

Life experience makes it fairly easy for each of us to guess when and where humans will make mistakes. Human errors tend to come at the edges of someone’s knowledge: Most of us would make mistakes solving calculus problems. We expect human mistakes to be clustered: A single calculus mistake is likely to be accompanied by others. We expect mistakes to wax and wane, predictably depending on factors such as fatigue and distraction. And mistakes are often accompanied by ignorance: Someone who makes calculus mistakes is also likely to respond “I don’t know” to calculus-related questions.

To the extent that AI systems make these human-like mistakes, we can bring all of our mistake-correcting systems to bear on their output. But the current crop of AI models—particularly LLMs—make mistakes differently.

AI errors come at seemingly random times, without any clustering around particular topics. LLM mistakes tend to be more evenly distributed through the knowledge space. A model might be equally likely to make a mistake on a calculus question as it is to propose that cabbages eat goats.

And AI mistakes aren’t accompanied by ignorance. A LLM will be just as confident when saying something completely wrong—and obviously so, to a human—as it will be when saying something true. The seemingly random inconsistency of LLMs makes it hard to trust their reasoning in complex, multi-step problems. If you want to use an AI model to help with a business problem, it’s not enough to see that it understands what factors make a product profitable; you need to be sure it won’t forget what money is.

How to Deal with AI Mistakes

This situation indicates two possible areas of research. The first is to engineer LLMs that make more human-like mistakes. The second is to build new mistake-correcting systems that deal with the specific sorts of mistakes that LLMs tend to make.

We already have some tools to lead LLMs to act in more human-like ways. Many of these arise from the field of “alignment” research, which aims to make models act in accordance with the goals and motivations of their human developers. One example is the technique that was arguably responsible for the breakthrough success of ChatGPT: reinforcement learning with human feedback. In this method, an AI model is (figuratively) rewarded for producing responses that get a thumbs-up from human evaluators. Similar approaches could be used to induce AI systems to make more human-like mistakes, particularly by penalizing them more for mistakes that are less intelligible.

When it comes to catching AI mistakes, some of the systems that we use to prevent human mistakes will help. To an extent, forcing LLMs to double-check their own work can help prevent errors. But LLMs can also confabulate seemingly plausible, but truly ridiculous, explanations for their flights from reason.

Other mistake mitigation systems for AI are unlike anything we use for humans. Because machines can’t get fatigued or frustrated in the way that humans do, it can help to ask an LLM the same question repeatedly in slightly different ways and then synthesize its multiple responses. Humans won’t put up with that kind of annoying repetition, but machines will.

Understanding Similarities and Differences

Researchers are still struggling to understand where LLM mistakes diverge from human ones. Some of the weirdness of AI is actually more human-like than it first appears. Small changes to a query to an LLM can result in wildly different responses, a problem known as prompt sensitivity. But, as any survey researcher can tell you, humans behave this way, too. The phrasing of a question in an opinion poll can have drastic impacts on the answers.

LLMs also seem to have a bias towards repeating the words that were most common in their training data; for example, guessing familiar place names like “America” even when asked about more exotic locations. Perhaps this is an example of the human “availability heuristic” manifesting in LLMs, with machines spitting out the first thing that comes to mind rather than reasoning through the question. And like humans, perhaps, some LLMs seem to get distracted in the middle of long documents; they’re better able to remember facts from the beginning and end. There is already progress on improving this error mode, as researchers have found that LLMs trained on more examples of retrieving information from long texts seem to do better at retrieving information uniformly.

In some cases, what’s bizarre about LLMs is that they act more like humans than we think they should. For example, some researchers have tested the hypothesis that LLMs perform better when offered a cash reward or threatened with death. It also turns out that some of the best ways to “jailbreak” LLMs (getting them to disobey their creators’ explicit instructions) look a lot like the kinds of social engineering tricks that humans use on each other: for example, pretending to be someone else or saying that the request is just a joke. But other effective jailbreaking techniques are things no human would ever fall for. One group found that if they used ASCII art (constructions of symbols that look like words or pictures) to pose dangerous questions, like how to build a bomb, the LLM would answer them willingly.

Humans may occasionally make seemingly random, incomprehensible, and inconsistent mistakes, but such occurrences are rare and often indicative of more serious problems. We also tend not to put people exhibiting these behaviors in decision-making positions. Likewise, we should confine AI decision-making systems to applications that suit their actual abilities—while keeping the potential ramifications of their mistakes firmly in mind.

This essay was written with Nathan E. Sanders, and originally appeared in IEEE Spectrum.

EDITED TO ADD (1/24): Slashdot thread.

Crank (person)

Post Syndicated from Григор original http://www.gatchev.info/blog/?p=2648

This is the bare text of an article in Wikipedia, deleted about an year ago.

I believe that it is significant – in fact, highly significant these days – and have put the text here to preserve it. Like all content of Wikipedia, it is licensed under CC-BY-SA, giving me the right to do so.

Authorship goes to the respective authors.

—-

Crank is a pejorative term used for a person who holds an unshakable belief that most of their contemporaries consider to be false.[1] Common synonyms for crank include crackpot and kook. A crank belief is so wildly at variance with those commonly held that it is considered ludicrous. Cranks characteristically dismiss all evidence or arguments which contradict their own unconventional beliefs, making any rational debate a futile task and rendering them impervious to facts, evidence, and rational inference.

A crank differs from a fanatic in that the subject of the fanatic’s obsession is either not necessarily widely regarded as wrong or not necessarily a “fringe” belief. Similarly, the word quack is reserved for someone who promotes a medical remedy or practice that is widely considered to be ineffective; this term, however, does not imply any deep belief in the idea or product they are attempting to sell.

Although experts in the field find a crank’s beliefs ridiculous, cranks are sometimes very successful in convincing non-experts of their views. A famous example is the Indiana Pi Bill, by which a state legislature nearly wrote into law a crank result in geometry.

Common characteristics

The second book of the mathematician and popular author Martin Gardner was a study of crank beliefs, Fads and Fallacies in the Name of Science. More recently, the mathematician Underwood Dudley has written a series of books on mathematical cranks, including The Trisectors, Mathematical Cranks, and Numerology: Or, What Pythagoras Wrought. And in a 1992 UseNet post, the mathematician John Baez humorously proposed a checklist, the Crackpot index, intended to diagnose cranky beliefs regarding contemporary physics.[2]

According to these authors, virtually universal characteristics of cranks include:

– Cranks overestimate their own knowledge and ability, and underestimate that of acknowledged experts.
– Cranks insist that their alleged discoveries are urgently important.
– Cranks rarely, if ever, acknowledge any error, no matter how trivial.

Cranks love to talk about their own beliefs, often in inappropriate social situations, but they tend to be bad listeners, being uninterested in anyone else’s experience or opinions.
Some cranks lack academic achievement, in which case they typically assert that academic training in the subject of their crank belief is not only unnecessary for discovering the truth, but actively harmful because they believe it poisons the minds by teaching falsehoods. Others greatly exaggerate their personal achievements, and may insist that some achievement (real or alleged) in some entirely unrelated area of human endeavor implies that their cranky opinion should be taken seriously.

Some cranks claim vast knowledge of any relevant literature, while others claim that familiarity with previous work is entirely unnecessary.

In addition, the overwhelming majority of cranks:

– seriously misunderstand the mainstream opinion to which they believe that they are objecting,
stress that they have been working out their ideas for many decades, and claim that this fact alone shows that their belief cannot be dismissed as resting upon some simple error,
– compare themselves with luminaries in their chosen field (often Galileo Galilei, Nicolaus Copernicus, Leonhard Euler, Isaac Newton, Albert Einstein or Georg Cantor),[citation needed] implying that the mere unpopularity of some belief is not good reason for it to be dismissed,
– claim that their ideas are being suppressed, typically backed up by conspiracy theories invoking intelligence organizations, mainstream science, powerful business interests, or other groups which, they allege, are terrified by the possibility of their revolutionary insights becoming widely known,
appear to regard themselves as persons of unique historical importance.

Cranks who contradict some mainstream opinion in some highly technical field, (e.g. mathematics, cryptography, physics) may:

– exhibit a marked lack of technical ability,
– misunderstand or not use standard notation and terminology,
– ignore fine distinctions which are essential to correctly understand mainstream belief.

That is, cranks tend to ignore any previous insights which have been proven by experience to facilitate discussion and analysis of the topic of their cranky claims; indeed, they often assert that these innovations obscure rather than clarify the situation.[3]

In addition, cranky scientific theories often do not in fact qualify as theories as this term is commonly understood within science. For example, crank theories in physics typically fail to result in testable predictions, which makes them unfalsifiable and hence unscientific. Or, cranks may present their ideas in such a confused, not even wrong manner that it is impossible to determine what they are actually claiming.

Internet cranks
(See also: Usenet personality)

The rise of the Internet has given another outlet to people well outside the mainstream who may get labeled cranks due to internet postings or websites promoting particular beliefs. There are a number of websites devoted to listing people as cranks. Community-edited websites like Wikipedia have been described as vulnerable to cranks.[4][5]

Science fiction author and critic Bruce Sterling noted in his essay in CATSCAN 13:

Online communication can wonderfully liberate the tender soul of some well-meaning personage who, for whatever reason, is physically uncharismatic. Unfortunately, online communication also fertilizes the eccentricities of hopeless cranks, who at last find themselves in firm possession of a wondrous soapbox that the Trilateral Commission and the Men In Black had previously denied them.[6]

There are also newsgroups which are nominally devoted to discussing (alt.usenet.kooks) or poking fun at (alt.slack, alt.religion.kibology) supposed cranks.

Crank magnetism

The term crank magnetism was coined by physiologist and blogger Mark Hoofnagle on the Denialism Blog in 2007 to refer to the tendency for cranks to be attracted to claims made by other cranks.[7] Crank magnetism may be considered to operate wherever a single person propounds a number of unrelated denialist conjectures, poorly supported conspiracy theories, or pseudoscientific claims. Thus, some of the common crank characteristics—such as the lack of technical ability, ignorance of scientific terminology, and claims that alternative ideas are being suppressed by the mainstream—may be operating on and manifested in multiple orthogonal assertions.

Hoofnagle’s fellow blogger David Gorski has discussed crank magnetism in relation to the writings of British columnist Melanie Phillips, who he alleges denies anthropogenic global warming while promoting intelligent design and the discredited view that the MMR vaccine causes autism in children.[8] Blogger Luke Scientiæ has commented on the relationship between the number of unrelated claims that magnetic cranks make and the extent of their open hostility to science.[9] He has also coined the phrase “magnetic hoax” in relation to hoax claims that attract multiple crank interpretations.[10]

Studies

One study, NASA faked the moon landing—Therefore (Climate) Science is a Hoax: An Anatomy of the Motivated Rejection of Science, gave evidence that climate change denial correlated with moon landing and 9/11 conspiracy theories, staunch beliefs in laissez-faire free-market capitalism, denial of the link between tobacco smoking and lung cancer, HIV/AIDS denialism and MLK death conspiracy theories:[11]

Although nearly all domain experts agree that human CO2 emissions are altering the world’s climate, segments of the public remain unconvinced by the scientific evidence. Internet blogs have become a vocal platform for climate denial, and bloggers have taken a prominent and influential role in questioning climate science. We report a survey (N > 1100) of climate blog users to identify the variables underlying acceptance and rejection of climate science. Paralleling previous work, we find that endorsement of a laissez-faire conception of free-market economics predicts rejection of climate science (r ‘ .80 between latent constructs). Endorsement of the free market also predicted the rejection of other established scientific findings, such as the facts that HIV causes AIDS and that smoking causes lung cancer. We additionally show that endorsement of a cluster of conspiracy theories (e.g., that the CIA killed Martin-Luther King or that NASA faked the moon landing) predicts rejection of climate science as well as the rejection of other scientific findings, above and beyond endorsement of laissez-faire free markets. This provides empirical confirmation of previous suggestions that conspiracist ideation contributes to the rejection of science. Acceptance of science, by contrast, was strongly associated with the perception of a consensus among scientists.[11]

Another study titled Dead and Alive: Beliefs in Contradictory Conspiracy Theories managed to show that not only will cranks be attracted to and believe in numerous conspiracy theories all at once, but will continue to do so even if the theories in question are completely and utterly incompatible with one another.[12] For instance, the study showed that: “… the more participants believed that Princess Diana faked her own death, the more they believed that she was murdered [and that] … the more participants believed that Osama Bin Laden was already dead when U.S. special forces raided his compound in Pakistan, the more they believed he is still alive,” and that “Hierarchical regression models showed that mutually incompatible conspiracy theories are positively associated because both are associated with the view that the authorities are engaged in a cover-up”.[12]

Studies such as Belief in Conspiracy Theories state that conspiracy theories relating to the assassination of JFK, the moon landing and the September 11th attacks are united by a common thread: distrust of the government-endorsed story. This leads the believer to attach other conspiracies as well. Someone with a distrust of the government will likely reject any stories or reports directly issued by state agencies or other authorities that are seen as part of the establishment. Thus, any conspiracy will seem more plausible to the conspiracy theorist because this fits with their worldview.[13]

Cultic milieu

In academic sociology, a similar notion to crank magnetism exists, namely Colin Campbell’s concept of the cultic milieu, which he used:

…to refer to a society’s deviant belief systems and practices and their associated collectivities, institutions, individuals, and media of communication. He described it as including “the worlds of the occult and the magical, of spiritualism and psychic phenomena, of mysticism and new thought, of alien intelligences and lost civilizations, of faith healing and nature cure” (Campbell 1972:122), and it can be seen, more generally, to be the point at which deviant science meets deviant religion. What unifies these diverse elements, apart from a consciousness of their deviant status and an ensuing sense of common cause, is an overlapping communication structure of magazines, pamphlets, lectures, and informal meetings, together with the common ideology of seekership.[14]

See also:

Creativity and mental illness
Eccentricity (behavior)
Illusory superiority
Dunning–Kruger effect
List of topics characterized as pseudoscience
Paranoia
Pseudophysics
Pseudoscholarship
Tallinna narrid ja narrikesed
Spoofs
Kibo
Psychoceramics

References:

Crank at Merriam-Webster Online Dictionary
John Baez, New improved crackpot index an update to the 1992 list, 26 August 1998, sci.physics (archived message on Google Groups).
Hodges, Wilfrid (1998). “An Editor Recalls Some Hopeless Papers”. The Bulletin of Symbolic Logic. 4 (1): 1–16. CiteSeerX 10.1.1.27.6154. doi:10.2307/421003. JSTOR 421003. S2CID 14897182. A paper describing several attempts at disproving Cantor’s diagonal argument, looking at the flaws in their arguments and reasoning.
“Fact or fiction? Who contributes to Wikipedia? Despite … Archived 2009-01-12 at the Wayback Machine”, Global Agenda, March 12, 2007, Retrieved 23 April 2010
“Wikipedia.(Brief Article)”. Booklist. September 15, 2002. Archived from the original on January 12, 2009. Retrieved May 11, 2008.
CATSCAN 13: “Electronic Text” Archived 2012-04-06 at the Wayback Machine (Bruce Sterling, SF Eye) Retrieved 8 August 2012
Hoofnagle, Mark. “Crank Magnetism”. Retrieved 25 November 2015.
Gorski, David (6 May 2009). “Melanie Phillips: Crank magnetism in action on evolution and vaccines”. Respectful Insolence. Retrieved 25 November 2015.
Luke Scientiæ. “A Few Comments on Crank Magnetism”. Retrieved 15 August 2011.[permanent dead link]
Luke Scientiae. “The Magnetic Hoax: The Giant Hoax as an Example”. Retrieved 15 August 2011.[permanent dead link]
Stephan Lewandowsky, Klaus Oberauer, Gilles Gignac. “NASA faked the moon landing – Therefore (Climate) Science is a Hoax: An Anatomy of the Motivated Rejection of Science.” Archived 31 July 2019 at the Wayback Machine Psychological Science (in press)
Michael J. Wood, Karen M. Douglas, Robbie M. Sutton. “Dead and Alive: Beliefs in Contradictory Conspiracy Theories” Archived 2018-01-05 at the Wayback Machine Social Psychological and Personality Science (in press)
Ted Goertzel. Belief in Conspiracy Theories. International Society of Political Psychology, vol. 15, no. 4, 1994. doi:10.2307/3791630
“Cult Archived 2016-03-04 at the Wayback Machine” William H. Swatos, Jr. Editor. Encyclopedia of Religion and Society, Hartford Institute for Religion Research.
Further reading
Dudley, Underwood (1987). A Budget of Trisections. New York: Springer-Verlag. ISBN 0387965688.
Dudley, Underwood (1992). Mathematical Cranks. Washington, D.C.: Mathematical Association of America. ISBN 0883855070.
Dudley, Underwood (1996). The Trisectors. Washington, D.C.: Mathematical Association of America. ISBN 0883855143.
Dudley, Underwood (1997). Numerology: Or, What Pythagoras Wrought. Washington, D.C.: Mathematical Association of America. ISBN 0883855240.
Dudley, Underwood (2008). On Jargon: How to Call a Crank a Crank (and Win If You Get Sued) (PDF). The UMAP Journal, 29.1.[permanent dead link]
Eves, Howard (1972). Mathematical Circles Squared; A Third Collection of Mathematical Stories and Anecdotes. Boston: Prindle, Weber & Schmidt. ISBN 0871501546.
Gardner, Martin (1957). Fads and Fallacies in the Name of Science. New York: Dover. ISBN 0486203948. LCCN 57003844.
Williams, William F. (Editor) (2000). Encyclopedia of Pseudoscience: From Alien Abductions to Zone Therapy Facts on File ISBN 081603351X
Kossy, Donna. Kooks: A Guide to the Outer Limits of Human Belief, Los Angeles: Feral House, 2001 (2nd ed. exp. from 1994). (ISBN 978-0922915675)
Kruger, Justin; David Dunning (1989). “Unskilled and Unaware of It: How Difficulties in Recognizing One’s Own Incompetence Lead to Inflated Self-Assessments” (PDF). J. Pers. Soc. Psychol. 71 (6): 1121–1134. doi:10.1037/0022-3514.77.6.1121. PMID 10626367.

External links:

Crank Dot Net: Cranks and their theories listed and categorised.