Tag Archives: Uncategorized

Upcoming Speaking Engagements

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/upcoming-speaking-engagements-38.html

This is a current list of where and when I am scheduled to speak:

  • I’m speaking—along with John Bruce, the CEO and Co-founder of Inrupt—at the 18th Annual CDOIQ Symposium in Cambridge, Massachusetts, USA. The symposium runs from July 16 through 18, 2024, and my session is on Tuesday, July 16 at 3:15 PM. The symposium will also be livestreamed through the Whova platform.
  • I’m speaking on “Reimagining Democracy in the Age of AI” at the Bozeman Library in Bozeman, Montana, USA, July 18, 2024. The event will also be available via Zoom.
  • I’m speaking at the TEDxBillings Democracy Event in Billings, Montana, USA, on July 19, 2024.

The list is maintained on this page.

Friday Squid Blogging: 1994 Lair of Squid Game

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/friday-squid-blogging-1994-lair-of-squid-game.html

I didn’t know:

In 1994, Hewlett-Packard released a miracle machine: the HP 200LX pocket-size PC. In the depths of the device, among the MS-DOS productivity apps built into its fixed memory, there lurked a first-person maze game called Lair of Squid.

[…]

In Lair of Squid, you’re trapped in an underwater labyrinth, seeking a way out while avoiding squid roaming the corridors. A collision with any cephalopod results in death. To progress through each stage and ascend to the surface, you locate the exit and provide a hidden, scrambled code word. The password is initially displayed as asterisks, with letters revealed as you encounter them within the maze.

Blog moderation policy.

The NSA Has a Long-Lost Lecture by Adm. Grace Hopper

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/the-nsa-has-a-long-lost-lecture-by-adm-grace-hopper.html

The NSA has a video recording of a 1982 lecture by Adm. Grace Hopper titled “Future Possibilities: Data, Hardware, Software, and People.” The agency is (so far) refusing to release it.

Basically, the recording is in an obscure video format. People at the NSA can’t easily watch it, so they can’t redact it. So they won’t do anything.

With digital obsolescence threatening many early technological formats, the dilemma surrounding Admiral Hopper’s lecture underscores the critical need for and challenge of digital preservation. This challenge transcends the confines of NSA’s operational scope. It is our shared obligation to safeguard such pivotal elements of our nation’s history, ensuring they remain within reach of future generations. While the stewardship of these recordings may extend beyond the NSA’s typical purview, they are undeniably a part of America’s national heritage.

Surely we can put pressure on them somehow.

Apple Is Alerting iPhone Users of Spyware Attacks

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/apple-is-alerting-iphone-users-of-spyware-attacks.html

Not a lot of details:

Apple has issued a new round of threat notifications to iPhone users across 98 countries, warning them of potential mercenary spyware attacks. It’s the second such alert campaign from the company this year, following a similar notification sent to users in 92 nations in April.

RADIUS Vulnerability

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/radius-vulnerability.html

New attack against the RADIUS authentication protocol:

The Blast-RADIUS attack allows a man-in-the-middle attacker between the RADIUS client and server to forge a valid protocol accept message in response to a failed authentication request. This forgery could give the attacker access to network devices and services without the attacker guessing or brute forcing passwords or shared secrets. The attacker does not learn user credentials.

This is one of those vulnerabilities that comes with a cool name, its own website, and a logo.

News article. Research paper.

Reverse-Engineering Ticketmaster’s Barcode System

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/reverse-engineering-ticketmasters-barcode-system.html

Interesting:

By reverse-engineering how Ticketmaster and AXS actually make their electronic tickets, scalpers have essentially figured out how to regenerate specific, genuine tickets that they have legally purchased from scratch onto infrastructure that they control. In doing so, they are removing the anti-scalping restrictions put on the tickets by Ticketmaster and AXS.

EDITED TO ADD (7/14): More information.

On the CSRB’s Non-Investigation of the SolarWinds Attack

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/on-the-csrbs-non-investigation-of-the-solarwinds-attack.html

ProPublica has a long investigative article on how the Cyber Safety Review Board failed to investigate the SolarWinds attack, and specifically Microsoft’s culpability, even though they were directed by President Biden to do so.

New Open SSH Vulnerability

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/new-open-ssh-vulnerability.html

It’s a serious one:

The vulnerability, which is a signal handler race condition in OpenSSH’s server (sshd), allows unauthenticated remote code execution (RCE) as root on glibc-based Linux systems; that presents a significant security risk. This race condition affects sshd in its default configuration.

[…]

This vulnerability, if exploited, could lead to full system compromise where an attacker can execute arbitrary code with the highest privileges, resulting in a complete system takeover, installation of malware, data manipulation, and the creation of backdoors for persistent access. It could facilitate network propagation, allowing attackers to use a compromised system as a foothold to traverse and exploit other vulnerable systems within the organization.

Moreover, gaining root access would enable attackers to bypass critical security mechanisms such as firewalls, intrusion detection systems, and logging mechanisms, further obscuring their activities. This could also result in significant data breaches and leakage, giving attackers access to all data stored on the system, including sensitive or proprietary information that could be stolen or publicly disclosed.

This vulnerability is challenging to exploit due to its remote race condition nature, requiring multiple attempts for a successful attack. This can cause memory corruption and necessitate overcoming Address Space Layout Randomization (ASLR). Advancements in deep learning may significantly increase the exploitation rate, potentially providing attackers with a substantial advantage in leveraging such security flaws.

The details. News articles. CVE data. Slashdot thread.

Upcoming Book on AI and Democracy

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/upcoming-book-on-ai-and-democracy.html

If you’ve been reading my blog, you’ve noticed that I have written a lot about AI and democracy, mostly with my co-author Nathan Sanders. I am pleased to announce that we’re writing a book on the topic.

This isn’t a book about deep fakes, or misinformation. This is a book about what happens when AI writes laws, adjudicates disputes, audits bureaucratic actions, assists in political strategy, and advises citizens on what candidates and issues to support. It’s a book that tries to look into what an AI-assisted democratic system might look like, and then at how to best ensure that we make use of the good parts while avoiding the bad parts.

This is what I talked about in my RSA Conference speech last month, which you can both watch and read. (You can also read earlier attempts at this idea.)

The book will be published by MIT Press sometime in fall 2025, with an open-access digital version available a year after that. (It really can’t be published earlier. Nothing published this year will rise above the noise of the US presidential election, and anything published next spring will have to go to press without knowing the results of that election.)

Right now, the organization of the book is in six parts:

AI-Assisted Politicians
AI-Assisted Legislators
The AI-Assisted Administration
The AI-Assisted Legal System
AI-Assisted Citizens
Getting the Future We Want

It’s too early to share a more detailed table of contents, but I would like help thinking about titles. Below are my current list of brainstorming ideas: both titles and subtitles. Please mix and match, or suggest your own in the comments. No idea is too far afield, because anything can spark more ideas.

Titles:

AI and Democracy
Democracy with AI
Democracy after AI
Democratia ex Machina
Democracy ex Machina
E Pluribus, Machina
Democracy and the Machines
Democracy with Machines
Building Democracy with Machines
Democracy in the Loop
We the People + AI
Artificial Democracy
AI Enhanced Democracy
The State of AI
Citizen AI

Trusting the Bots
Trusting the Computer
Trusting the Machine

The End of the Beginning
Sharing Power
Better Run
Speed, Scale, Scope, and Sophistication
The New Model of Governance
Model Citizen
Artificial Individualism

Subtitles:

How AI Upsets the Power Balances of Democracy
Twenty (or So) Ways AI will Change Democracy
Reimagining Democracy for the Age of AI
Who Wins and Loses
How Democracy Thrives in an AI-Enhanced World
Ensuring that AI Enhances Democracy and Doesn’t Destroy It
How AI Will Change Politics, Legislating, Bureaucracy, Courtrooms, and Citizens
AI’s Transformation of Government, Citizenship, and Everything In-Between
Remaking Democracy, from Voting to Legislating to Waiting in Line
How to Make Democracy Work for People in an AI Future
How AI Will Totally Reshape Democracies and Democratic Institutions
Who Wins and Loses when AI Governs
How to Win and Not Lose With AI as a Partner
AI’s Transformation of Democracy, for Better and for Worse
How AI Can Improve Society and Not Destroy It
How AI Can Improve Society and Not Subvert It
Of the People, for the People, with a Whole lot of AI
How AI Will Reshape Democracy
How the AI Revolution Will Reshape Democracy

Combinations:

Imagining a Thriving Democracy in the Age of AI: How Technology Enhances Democratic Ideals and Nurtures a Society that Serves its People

Making Model Citizens: How to Put AI to Use to Help Democracy
Modeling Citizenship: Who Wins and Who Loses when AI Transforms Democracy
A Model for Government: Democracy with AI, and How to Make it Work for Us

AI of, By, and for the People: How Artificial Intelligence will reshape Democracy
The (AI) Political Revolution: Speed, Scale, Scope, Sophistication, and our Democracy
Speed, Scale, Scope, Sophistication: The AI Democratic Revolution
The Artificial Political Revolution: X Ways AI will Change Democracy…Forever

EDITED TO ADD (7/10): More options:

The Silicon Realignment: The Future of Political Power in a Digital World
Political Machines
EveryTHING is political

Model Extraction from Neural Networks

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/model-extraction-from-neural-networks.html

A new paper, “Polynomial Time Cryptanalytic Extraction of Neural Network Models,” by Adi Shamir and others, uses ideas from differential cryptanalysis to extract the weights inside a neural network using specific queries and their results. This is much more theoretical than practical, but it’s a really interesting result.

Abstract:

Billions of dollars and countless GPU hours are currently spent on training Deep Neural Networks (DNNs) for a variety of tasks. Thus, it is essential to determine the difficulty of extracting all the parameters of such neural networks when given access to their black-box implementations. Many versions of this problem have been studied over the last 30 years, and the best current attack on ReLU-based deep neural networks was presented at Crypto’20 by Carlini, Jagielski, and Mironov. It resembles a differential chosen plaintext attack on a cryptosystem, which has a secret key embedded in its black-box implementation and requires a polynomial number of queries but an exponential amount of time (as a function of the number of neurons). In this paper, we improve this attack by developing several new techniques that enable us to extract with arbitrarily high precision all the real-valued parameters of a ReLU-based DNN using a polynomial number of queries and a polynomial amount of time. We demonstrate its practical efficiency by applying it to a full-sized neural network for classifying the CIFAR10 dataset, which has 3072 inputs, 8 hidden layers with 256 neurons each, and about 1.2 million neuronal parameters. An attack following the approach by Carlini et al. requires an exhaustive search over 2^256 possibilities. Our attack replaces this with our new techniques, which require only 30 minutes on a 256-core computer.

The US Is Banning Kaspersky

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/06/the-us-is-banning-kaspersky.html

This move has been coming for a long time.

The Biden administration on Thursday said it’s banning the company from selling its products to new US-based customers starting on July 20, with the company only allowed to provide software updates to existing customers through September 29. The ban—­the first such action under authorities given to the Commerce Department in 2019­—follows years of warnings from the US intelligence community about Kaspersky being a national security threat because Moscow could allegedly commandeer its all-seeing antivirus software to spy on its customers.

Best practices working with self-hosted GitHub Action runners at scale on AWS

Post Syndicated from Shilpa Sharma original https://aws.amazon.com/blogs/devops/best-practices-working-with-self-hosted-github-action-runners-at-scale-on-aws/

Overview

GitHub Actions is a continuous integration and continuous deployment platform that enables the automation of build, test and deployment activities for your workload. GitHub Self-Hosted Runners provide a flexible and customizable option to run your GitHub Action pipelines. These runners allow you to run your builds on your own infrastructure, giving you control over the environment in which your code is built, tested, and deployed. This reduces your security risk and costs, and gives you the ability to use specific tools and technologies that may not be available in GitHub hosted runners. In this blog, I explore security, performance and cost best practices to take into consideration when deploying GitHub Self-Hosted Runners to your AWS environment.

Best Practices

Understand your security responsibilities

GitHub Self-hosted runners, by design, execute code defined within a GitHub repository, either through the workflow scripts or through the repository build process. You must understand that the security of your AWS runner execution environments are dependent upon the security of your GitHub implementation. Whilst a complete overview of GitHub security is outside the scope of this blog, I recommended that before you begin integrating your GitHub environment with your AWS environment, you review and understand at least the following GitHub security configurations.

  • Federate your GitHub users, and manage the lifecycle of identities through a directory.
  • Limit administrative privileges of GitHub repositories, and restrict who is able to administer permissions, write to repositories, modify repository configurations or install GitHub Apps.
  • Limit control over GitHub Actions runner registration and group settings
  • Limit control over GitHub workflows, and follow GitHub’s recommendations on using third-party actions
  • Do not allow public repositories access to self-hosted runners

Reduce security risk with short-lived AWS credentials

Make use of short-lived credentials wherever you can. They expire by default within 1 hour, and you do not need to rotate or explicitly revoke them. Short lived credentials are created by the AWS Security Token Service (STS). If you use federation to access your AWS account, assume roles, or use Amazon EC2 instance profiles and Amazon ECS task roles, you are using STS already!

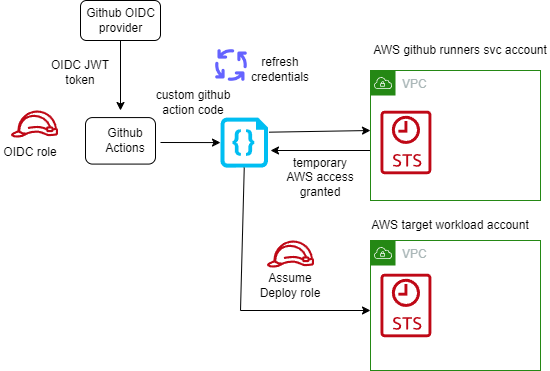
In almost all cases, you do not need long-lived AWS Identity and Access Management (IAM) credentials (access keys) even for services that do not “run” on AWS – you can extend IAM roles to workloads outside of AWS without requiring you to manage long-term credentials. With GitHub Actions, we suggest you use OpenID Connect (OIDC). OIDC is a decentralized authentication protocol that is natively supported by STS using sts:AssumeRoleWithWebIdentity, GitHub and many other providers. With OIDC, you can create least-privilege IAM roles tied to individual GitHub repositories and their respective actions. GitHub Actions exposes an OIDC provider to each action run that you can utilize for this purpose.

Short lived AWS credentials with GitHub self-hosted runners

Short lived AWS credentials with GitHub self-hosted runners

If you have many repositories that you wish to grant an individual role to, you may run into a hard limit of the number of IAM roles in a single account. While I advocate solving this problem with a multi-account strategy, you can alternatively scale this approach by:

  • using attribute based access control (ABAC) to match claims in the GitHub token (such as repository name, branch, or team) to the AWS resource tags.
  • using role based access control (RBAC) by logically grouping the repositories in GitHub into Teams or applications to create fewer subset of roles.
  • use an identity broker pattern to vend credentials dynamically based on the identity provided to the GitHub workflow.

Use Ephemeral Runners

Configure your GitHub Action runners to run in “ephemeral” mode, which creates (and destroys) individual short-lived compute environments per job on demand. The short environment lifespan and per-build isolation reduces the risk of data leakage , even in multi-tenanted continuous integration environments, as each build job remains isolated from others on the underlying host.

As each job runs on a new environment created on demand, there is no need for a job to wait for an idle runner, simplifying auto-scaling. With the ability to scale runners on demand, you do not need to worry about turning build infrastructure off when it is not needed (for example out of office hours), giving you a cost-efficient setup. To optimize the setup further, consider allowing developers to tag workflows with instance type tags and launch specific instance types that are optimal for respective workflows.

There are a few considerations to take into account when using ephemeral runners:

  • A job will remain queued until the runner EC2 instance has launched and is ready. This can take up to 2 minutes to complete. To speed up this process, consider using an optimized AMI with all prerequisites installed.
  • Since each job is launched on a fresh runner, utilizing caching on the runner is not possible. For example, Docker images and libraries will always be pulled from source.

Use Runner Groups to isolate your runners based on security requirements

By using ephemeral runners in a single GitHub runner group, you are creating a pool of resources in the same AWS account that are used by all repositories sharing this runner group. Your organizational security requirements may dictate that your execution environments must be isolated further, such as by repository or by environment (such as dev, test, prod).

Runner groups allow you to define the runners that will execute your workflows on a repository-by-repository basis. Creating multiple runner groups not only allow you to provide different types of compute environments, but allow you to place your workflow executions in locations within AWS that are isolated from each other. For example, you may choose to locate your development workflows in one runner group and test workflows in another, with each ephemeral runner group being deployed to a different AWS account.

Runners by definition execute code on behalf of your GitHub users. At a minimum, I recommend that your ephemeral runner groups are contained within their own AWS account and that this AWS account has minimal access to other organizational resources. When access to organizational resources is required, this can be given on a repository-by-repository basis through IAM role assumption with OIDC, and these roles can be given least-privilege access to the resources they require.

Optimize runner start up time using Amazon EC2 warm-pools

Ephemeral runners provide strong build isolation, simplicity and security. Since the runners are launched on demand, the job will be required to wait for the runner to launch and register itself with GitHub. While this usually happens in under 2 minutes, this wait time might not be acceptable in some scenarios.

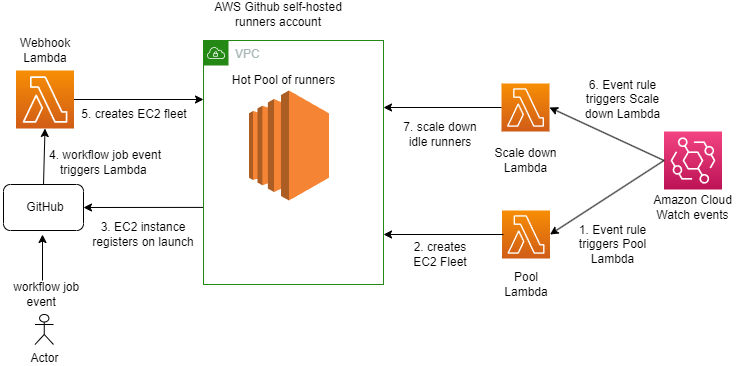
We can use a warm pool of pre-registered ephemeral runners to reduce the wait time. These runners will listen to the incoming GitHub workflow events actively and as soon as an incoming workflow event is queued, it is picked up readily by the warm pool of registered EC2 runners.

While there can be multiple strategies to manage the warm pool, I recommend the following strategy which uses AWS Lambda for scaling up and scaling down the ephemeral runners:

GitHub self-hosted runners warm pool flow

GitHub self-hosted runners warm pool flow

A GitHub workflow event is created on a trigger like push of code in a master repository or a merge of pull request. This event triggers a Lambda function via webhook and Amazon API Gateway endpoint. The Lambda function helps in validating the GitHub workflow event payload and log events for observability & building metrics. It can be used optionally to replenish the warm pool. There are separate backend Lambda functions to launch, scale up and scale down the warm pool of EC2 instances. The EC2 instances or runners are registered with GitHub at the time of launch. The registered runners listens for incoming GitHub work flow events using GitHub’s internal job queue and as soon as workflow events are triggered, its assigned by GitHub to one of the runners in warm pool for job execution. The runner is automatically de-registered once the job completes. A job can be a build, or deploy request as defined in your GitHub workflow.

With warm pool in place, it is expected to help reduce wait time by 70-80%.

Considerations

  • Increased complexity as there is a possibility of over provisioning runners. This will depend on how long a runner EC2 instance requires to launch and reach a ready state and how frequently the scale up Lambda is configured to run. For example, if the scale up Lambda runs every 1 minute and the EC2 runner requires 2 minutes to launch, then the scale up Lambda will launch 2 instances. The mitigation is to use Auto scaling groups to manage the EC2 warm pool and desired capacity with predictive scaling policies tying back to incoming GitHub workflow events i.e. build job requests.
  • This strategy may have to be revised when supporting Windows or Mac based runners given the spin up times can vary.

Use an optimized AMI to speed up the launch of GitHub self-hosted runners

Amazon Machine Images (AMI) provide a pre-configured, optimized image that can be used to launch the runner EC2 instance. By using AMIs, you will be able to reduce the launch time of a new runner since dependencies and tools are already installed. Consistency across builds is guaranteed due to all instances running the same version of dependencies and tools. Runners will benefit from increased stability and security compliance as images are tested and approved before being distributed for use as runner instances.

When building an AMI for use as a GitHub self-hosted runner the following considerations need to be made:

  • Choosing the right OS base image for the builds. This will depend on your tech stack and toolset.
  • Install the GitHub runner app as part of the image. Ensure automatic runner updates are enabled to reduce the overhead of managing running versions. In case a specific runner version must be used you can disable automatic runner updates to avoid untested changes. Keep in mind, if disabled, a runner will need to be updated manually within 30 days of a new version becoming available.
  • Install build tools and dependencies from trusted sources.
  • Ensure runner logs are captured and forwarded to your security information and event management (SIEM) of choice.
  • The runner requires internet connectivity to access GitHub. This may require configuring proxy settings on the instance depending on your networking setup.
  • Configure any artifact repositories the runner requires. This includes sources and authentication.
  • Automate the creation of the AMI using tools such as EC2 Image Builder to achieve consistency.

Use Spot instances to save costs

The cost associated with scaling up the runners as well as maintaining a hot pool can be minimized using Spot Instances, which can result in savings up to 90% compared to On-Demand prices. However, there could be requirements where we can have longer running builds or batch jobs that cannot tolerate the spot instance terminating on 2 minutes notice. So, having a mixed pool of instances will be a good option where such jobs should be routed to on-demand EC2 instances and the rest on the Spot instances to cater for diverse build needs. This can be done by assigning labels to the runner during launch /registration. In that case, the on-demand instances will be launched and we can a savings plan in place to get cost benefits.

Record runner metrics using Amazon CloudWatch for Observability

It is vital for the observability of the overall platform to generate metrics for the EC2 based GitHub self-hosted runners. Examples of the GitHub runners metrics can be: the number of GitHub workflow events queued or completed in a minute, or number of EC2 runners up and available in the warm pool etc.

We can log the triggered workflow events and runner logs in Amazon CloudWatch and then use CloudWatch embedded metrics to collect metrics such as number of workflow events queued, in progress and completed. Using elements like “started_at” and “completed_at” timings which are part of workflow event payload we can calculate build wait time.

As an example, below is the sample incoming GitHub workflow event logged in Amazon Cloud Watch Logs

<p> </p><p><code>{</code></p><p><code>"hostname": "xxx.xxx.xxx.xxx",</code></p><p><code>"requestId": "aafddsd55-fgcf555",</code></p><p><code>"date": "2022-10-11T05:50:35.816Z",</code></p><p><code>"logLevel": "info",</code></p><p><code>"logLevelId": 3,</code></p><p><code>"filePath": "index.js",</code></p><p><code>"fullFilePath": "/var/task/index.js",</code></p><p><code>"fileNa<a class="ab-item" href="https://aws-blogs-prod.amazon.com/devops/" aria-haspopup="true">AWS DevOps Blog</a>me": "index.js",</code></p><p><code>"lineNumber": 83889,</code></p><p><code>"columnNumber": 12,</code></p><p><code>"isConstructor": false,</code></p><p><code>"functionName": "handle",</code></p><p><code>"argumentsArray": [</code></p><p><code>"Processing Github event",</code></p><p><code>"{\"event\":\"workflow_job\",\"repository\":\"testorg-poc/github-actions-test-repo\",\"action\":\"queued\",\"name\":\"jobname-buildanddeploy\",\"status\":\"queued\",\"started_at\":\"2022-10-11T05:50:33Z\",\"completed_at\":null,\"conclusion\":null}"</code></p><p><code>]</code></p><p><code>}</code></p>

In order to use the logged elements of above log into metrics by capturing \”status\”:\”queued\”,\”repository\”:\”testorg-poc/github-actions-test-repo\c, \”name\”:\”jobname-buildanddeploy\” ,and workflow \”event\” , one can build embedded metrics in the application code or AWS metrics Lambda using any of the cloud watch metrics client library Creating logs in embedded metric format using the client libraries – Amazon CloudWatch based on the language of your choice listed.c

Essentially what one of those libraries will do under the hood is map elements from Log event into dimension fields so cloud watch can then read and generate a metric using that.

console.log(<br />      JSON.stringify({<br />        message: '[Embedded Metric]', // Identifier for metric logs in CW logs<br />        build_event_metric: 1, // Metric Name and value<br />        status: `${status}`, // Dimension name and value<br />        eventName: `${eventName}`,<br />        repository: `${repository}`,<br />        name: `${name}`,<br />        <br />        _aws: {<br />          Timestamp: Date.now(),<br />          CloudWatchMetrics: [<br />            {<br />              Namespace: `demo_2`,<br />              Dimensions: [['status','eventName','repository','name']],<br />              Metrics: [<br />                {<br />                  Name: 'build_event_metric',<br />                  Unit: 'Count',<br />                },<br />              ],<br />            },<br />          ],<br />        },<br />      })<br />    );

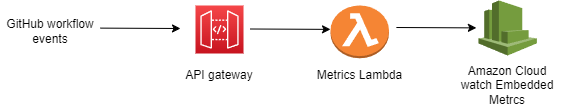
A sample architecture:

Consumption of GitHub webhook events

Consumption of GitHub webhook events

The cloud watch metrics can be published to your dashboards or forwarded to any external tool based on requirements. Once we have metrics, CloudWatch alarms and notifications can be configured to manage pool exhaustion.

Conclusion

In this blog post, we outlined several best practices covering security, scalability and cost efficiency when using GitHub Actions with EC2 self-hosted runners on AWS. We covered how using short-lived credentials combined with ephemeral runners will reduce security and build contamination risks. We also showed how runners can be optimized for faster startup and job execution AMIs and warm EC2 pools. Last but not least, cost efficiencies can be maximized by using Spot instances for runners in the right scenarios.

Resources:

How to use Mail Manager to Archive Inbound Emails

Post Syndicated from Sesan Komaiya original https://aws.amazon.com/blogs/messaging-and-targeting/archiving-and-sending-to-final-smtp-server/

In today’s digital landscape, where email communication plays a vital role in business operations, Keeping your email archive secure, compliant, and retrievable is crucial for any business. However, managing the large volume of email data can lead to operational difficulties, including regulatory compliance, maintaining an audit trail, and preventing data loss. That’s where Amazon Simple Email Service (SES) Mail Manager’s email archiving feature comes in.

In this blog post, we will explore how Amazon SES Mail Manager’s email archiving and search features can improve email security and compliance. If you’re a newcomer to Mail Manager, look at this blog post on Amazon SES Mail Manager. It provides valuable information on important features, such as Ingress Endpoint, Traffic Policy, Rule Sets, and SMTP Relay.

Problem Statement:

Imagine a scenario where a critical email from a key client is buried deep within your organization’s email archives, and you need to retrieve it for an important audit. The challenge of ensuring your business remains compliant with stringent data retention policies across every email communication for thousands of employees for a certain period or permanently.

Solution explained:

Amazon SES Mail Manager Email archiving is a powerful tool that addresses many of the challenges organizations face dealing with the difficulty and expense of archiving email at scale. Compliance and regulatory frameworks like GDPR, HIPAA, and SOX often require email archiving, which is a common objective identified by customers needing to comply with those regulatory frameworks. For regulated businesses, failure to comply with email archiving regulations can result in severe financial penalties and reputational damage.

Amazon SES Mail Manager securely archives and safeguards your emails, providing easy search and export functionality. It provides full-time, enterprise-level archiving without increasing the storage requirements of your mailbox server. The feature provides a reliable and efficient solution to address most compliance requirements. By automatically archiving the types of emails you specify, the service ensures that your organization maintains a comprehensive audit trail of its communications, enabling quick retrieval and review as needed.

The email archiving feature of Mail Manager provides organizations the ability to archive email while in transit rather than archiving at the user’s mailbox. Many organizations prefer archiving in transit for email archiving to meet compliance requirements and maintain comprehensive records. If you would like to learn more about in transit archiving, visit this blog –  Email Archiving with Mail Manager: Why To Archive In Transit vs At The Mailbox.

How email flows with an Amazon SES Mail Manager Email Archiving

For instructional purposes in this blog post, we’ll focus on how you can introduce Mail Manager archiving into your existing email infrastructure. We’ll cover how to seamlessly integrate Mail Manager with reference architectures. Later in the blog, we are going to explore Mail Manager’s archiving capabilities, including search, export and retention policies.

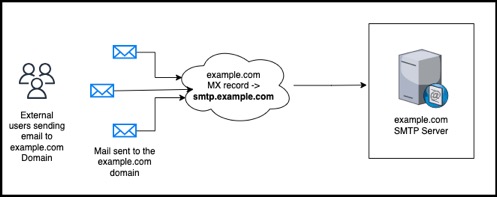
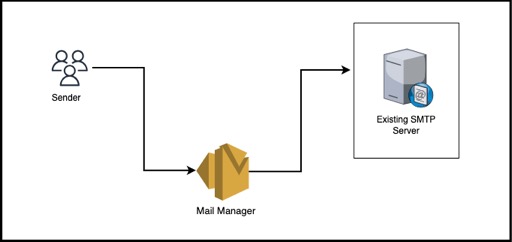
Current setup

Our example organization has an existing mail server (it might be a on-premises Microsoft Exchange Server, Microsoft 365, Google Workspace, etc). Their DNS is configured to route all email directly to this mail server. There is currently no archiving capacity within the existing email infrastructure, when needed, archiving is handled by individual mailbox users and PST files. While this method is suitable for personal email archiving, it fails to meet the organizations’ security requirements and compliance standards.

Figure 1: Example organization’s existing inbound email workflow.

Email Archiving in transit

We are going to introduce Mail Manager into the current mail flow (see figure 1) to archive all incoming messages from our example enterprise’s email infrastructure.

Figure 2: Example organization’s proposed inbound email workflow, with Mail Manager archiving in-transit prior to delivery.

In the new architecture (see figure 2), we’ve introduced Mail Manager into the organization’s inbound email workflow. This new workflow leverages Mail Manager’s ability to archive either all inbound emails, or only those that match specified criteria. By using a Mail Manager Rule set, our example organization can selectively store and preserve emails that meet their configured criteria.

Mail Manager Email Archiving and Search and Export Capabilities

Mail Manager’s archive search capabilities are designed to be user-friendly and efficient. You can perform searches based on various criteria, such as sender, recipient, subject line, date range, or even specific keywords in the Subject line. The search results provide options to either export the search to Amazon Simple Storage Service (S3), or you can choose to download a single email.

Let’s explore using Mail Manager’s archive search to find a specific email by the sender’s address:

Figure 3: Mail Manager’s archive search interface

Once found, we can click on the results to review the email in the console:

Figure 4: Mail Manager’s archive search results

Once we’ve found the target email, it can be downloaded by clicking on “View details“. The image below shows an example message details page with information about the email, including message headers such as In-Reply-To, X-Original-Mailer and X-Mailer.

Figure 5: Mail Manager’s archived email detailed page

Mail Manager’s archive search history tab allows us to find archive searches created in the last 30 days, and view the search results, as shown in the image below:

Figure 6: Mail Manager’s archive search history

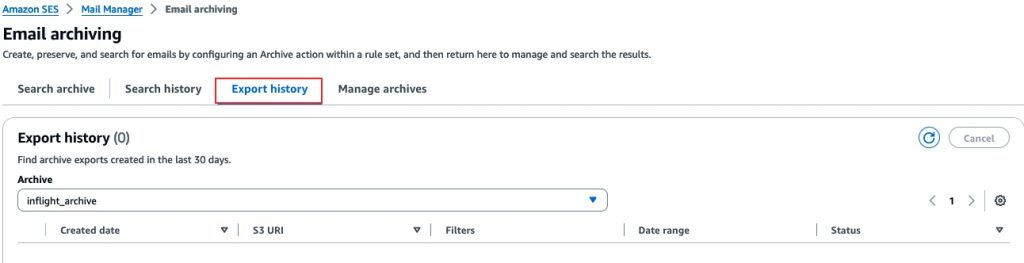
Mail Manager’s archive export history tab lists all of the archived email searches you exported to an Amazon S3 Bucket within the last 30 days.

Figure 7: Export History

Step by Step Setup:

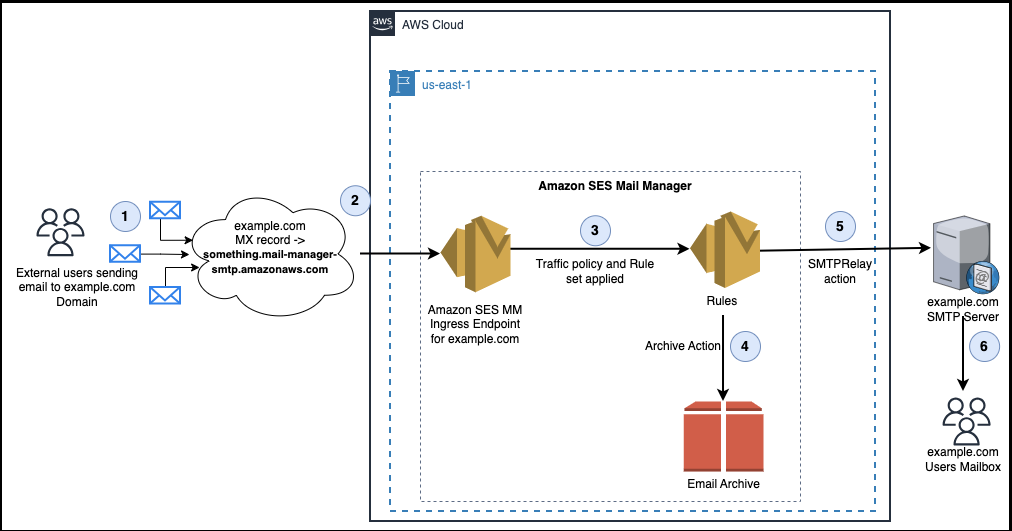
Now that we have explained how Mail Manger can be inserted into our example organization’s email workflow to provide email archiving, let’s explore how you can implement Mail Manager’s archiving capabilities in your inbound email workflows. The following diagram (Figure 3) illustrates the overall structure and components involved in this architecture:

Figure 8: End-to-End Mail workflow

Follow the steps below to configure Mail Manager in your AWS account to implement this architecture:

  1. Log into the SES Console and select Mal Manager from the left navigation menu.
    1. Note, as of this writing, Mail Manager is generally available in the following AWS Regions: US East (N. Virginia), US West (Oregon), Europe (Ireland, Frankfurt), Asia Pacific (Tokyo, Sydney).
  2. Under Mail Manger navigation, create an archive (or multiple archives for different use cases)
    1. Enter a unique name in the Archive name field.
    2. (Optional) Select a retention period in the Retention period field to override the default retention period of 180 days.
    3. (Optional) You can encrypt your archive either by entering your own AWS KMS key into the KMS key ARN field, or by selecting Create new key.
    4. Choose Create archive.
  3. Under Mail Manger navigation, create a traffic policy to determine the email you want to block or allow.
    1. Create traffic policy.
    2. On the Create a traffic policy page, enter a unique name for your traffic policy.
    3. (Optional) If you want to discard any messages above a certain size, enter a value in bytes in the Maximum message size field.
    4. In Default action, choose whether the traffic policy is to either Allow or Deny (block) messages that fall outside of (are not addressed by) the conditions of your policy statements.
    5. Select Add new policy statement to create a statement for your traffic policy.
    6. Choose either Allow or Deny (block) for the action to be taken when the statement’s conditions are met.
    7. Build a condition by selecting an email protocol and a conditional operator for the value you enter. Select Add new condition if you want to add more conditions to this policy statement. To learn more about a condition property and its operators and valid values, see the Policy statement conditions reference.
    8. If you’re subscribed to an Email Add On, you’ll be able to select it here as an email protocol.
    9. If you want add more policy statements and conditions, repeat steps above.
    10. Select Create traffic policy.
  4. Under Mail Manger navigation, create a rule set to perform actions on the email you allow in.
    1. Create rule set and enter a unique name for your rule set.
    2. Create new rule on the edit page.
    3. In the Rule details sidebar, enter a unique name for your rule.
    4. Select Add new condition to create a condition that the message must match; or check the EXCEPT in the case of: box followed by Add new exception to create a condition that the message must not match.
    5. Build the condition or exception by selecting an email property and a conditional operator for the value you enter. Select Add new condition or Add new exception if you want to add more conditions or exceptions to this rule. To learn more about a condition property and its operators and valid values, see the Rule conditions reference.
    6. Select Add new action to define the action to be taken when the rule’s conditions are matched and/or exceptions are not matched. To add more actions to be taken, select Add new action. To learn more about actions and their parameters, see the Rule actions reference.
    7. Create an Archive rule. Save rule set
  5. Under Mail Manger navigation, Create your ingress endpoint and assign to it the traffic policy and rule set.
    1. choose Ingress endpoints under Mail Manager.
    2. On the Ingress endpoints page, select Create ingress endpoint.
    3. On the Create new ingress endpoint page, enter a unique name for your ingress endpoint.
    4. Choose whether it will be a Open or Authenticated endpoint.
    5. Select a traffic policy to determine the email you want to block or allow.
    6. Select a rule set containing the rule actions you want to perform on the email you allow in.
    7. Select Create ingress endpoint.
  6. Configure your environment to use the ingress endpoint.
    1. At the time you create an ingress endpoint, an “A” record for the endpoint will be generated and its value displayed on the ingress endpoint’s summary screen in the SES console. The way you use the value of this record depends on the type of endpoint you created and your use case.
    2. DNS providers have different procedures and interfaces for configuring email records. The key pieces of information you need to put into your DNS settings are listed in our documentation – https://docs.aws.amazon.com/ses/latest/dg/eb-ingress.html#eb-ingress-a-record
  7. Under Mail Manger navigation, create an SMTP Relay to send mail on to your existing mail server.
    1. choose SMTP relays under Mail Manager.
    2. On the SMTP relays page, select Create SMTP relay.
    3. On the Create SMTP relay page, enter a unique name for your SMTP relay.
    4. Depending on what type of SMTP Realy you want to configure, follow the respective instructions:
      1. inbound (non-authenticated)
      2. outbound (authenticated) SMTP relay
  8. Update your DNS MX records to point to your new Mail Manager’s ingress point, instead of the existing mail server.

Note: Make sure that you have tested the steps above in your development environment and that you understand the steps before deploying into your production environment.

Conclusion

Amazon SES Mail Manager’s email archiving capabilities are designed for organizations that are seeking to enhance the security, compliance, and audit-ability of their email communications. By seamlessly integrating this feature into their existing email infrastructure, organizations can now archive all inbound messages in transit, ensuring a comprehensive, tamper-proof record of their email activities. The powerful search and export functionality of Mail Manager makes it easy to quickly locate and access specific emails when needed, whether for compliance audits, legal requests, or internal investigations.

This level of email visibility and control is particularly crucial for organizations operating in highly regulated industries like government, healthcare and finance, where the stakes for non-compliance can be severe. Beyond the compliance benefits, Mail Manager’s email archiving also helps to alleviate the operational headaches and expenses associated with traditional in-house archiving systems. By offloading this responsibility to AWS, organizations can focus their resources on their core business priorities, while still maintaining the security and accessibility of their critical email data.

If you’re looking to strengthen your email security posture, simplify your compliance efforts, and improve the overall management of your email archives, we encourage you to explore how Amazon SES Mail Manager’s email archiving capabilities can be seamlessly integrated into your existing email infrastructure. Take the first step towards a more secure, compliant, and efficient email management solution by contacting us today.

About the Authors

Sesan Komaiya

Sesan Komaiya

Sesan is a Solutions Architect at Amazon Web Services. He works with a variety of customers, helping them with cloud adoption, cost optimization and emerging technologies. Sesan has over 15 year’s experience in Enterprise IT and has been at AWS for 5 years. In his free time, Sesan enjoys watching various sporting activities like Soccer, Tennis and Moto sport. He has 2 kids that also keeps him busy at home.

Alexey Kurbatsky

Alexey Kurbatsky

Alexey is a Senior Software Development Engineer at AWS, specializing in building distributed and scalable services. Outside of work, he enjoys exploring nature thru hiking as well as playing guitar.

Jesse Thompson
Jesse Thompson is an Email Deliverability Manager with the Amazon Simple Email Service team. His background is in enterprise development and operations, with a focus on email abuse mitigation and encouragement of authenticity practices with open standard protocols. Jesse’s favorite activity outside of technology is recreational curling.
Zip

Zip

Zip is a Sr. Specialist Solutions Architect at AWS, working with Amazon Pinpoint and Simple Email Service and WorkMail. Outside of work he enjoys time with his family, cooking, mountain biking, boating, learning and beach plogging.

How to use SES Mail Manager SMTP Relay action to deliver inbound email to Google Workspace and Microsoft 365

Post Syndicated from Zip Zieper original https://aws.amazon.com/blogs/messaging-and-targeting/how-to-use-ses-mail-manager-smtp-relay-action-to-deliver-inbound-email-to-google-workspace-and-microsoft-365/

Introduction

Customers often ask us if the Amazon Simple Email Service (SES) inbound capabilities they use with applications hosted on AWS infrastructure can also be used to process and automate employee email hosted on public services like Google Workspace and Microsoft 365. The answer has typically been “yes, but with some limitations”, as until now, SES inbound has been somewhat constrained by the fact that it didn’t support relaying messages for an existing domain. This limitation makes it very difficult to fully manage email flows across hybrid email environments.

Such conversations led the SES team to create Amazon Simple Email Service (SES) Mail Manager which offers a set of capabilities that simplify managing large volumes of email communications within an organization. Mail Manager’s rules set conditions and actions can optimize routing for improved delivery and communication flow, both for incoming and outgoing emails. Mail Manager’s email security features can be augmented by optional add-ons from industry-leading, vetted third-party providers. Flexible archiving features help organizations meet stringent compliance and record-keeping requirements.

In this blog, we position Mail Manager as a central ingress gateway for a fictitious company, Nutrition.co, that is based on real-world AWS customers. We discuss the customer challenges and explain how to configure Mail Manager’s SMTP Relay action to intercept, archive then deliver emails destined for employees’ Google Workspace hosted Gmail and Microsoft 365 hosted Exchange Online mailboxes. Similar mail flows can be used to process, automate and archive emails destined for their AWS hosted apps.

You can learn more about all of Mail Manager’s capabilities here.

Customer background and use case

Our fictitious company, Nutrition.co, is an online retail business with multiple employee departments, including administration, marketing, sales and fulfillment. The company has acquired several smaller rivals that use both Google Workspace and Microsoft 365 to host their employee inboxes, and plan to consolidate all users onto the same domain ( such as [email protected] and [email protected]). They also host several applications on Amazon Web Services (AWS) that use Amazon SES’ inbound capability to receive emails using a subdomain *customer-support*.nutrition.co, such as orders@*customer-support*.nutrition.co and returns@*customer-support*.nutrition.co.

Nutrition.co is looking for a solution to unify all their email domain routing, security and archiving processes onto one centralized management system to simplify their email infrastructure. They want an approach that provides more flexibility to control which addresses and domains are used for apps and automation as well as employee mail. They also want to enhance email compliance and governance with a flexible solution for screening, processing and archiving inbound emails to both employees and applications, before delivering those emails to recipient inboxes on Google Workspace and Microsoft 365 and applications hosted on AWS.

The SES Mail Manger based central ingress and egress gateway architecture we propose will allow Nutrition.co to manage their peer-to-peer and application-driven emails in one place, Amazon SES. It will simplify email security and management, and make it easy to unlock new cloud-enabled email use cases. The architecture can be modified to acommodate a wide variety of email infrastructure, including fully cloud hosted, on-premises, and hybrid mailbox hosting environments.

What is an Inbound SMTP Gateway?

An Inbound SMTP Gateway is an SMTP server that accepts inbound email via an Open Ingress Point, and then delivers those messages to another email environment’s inbound SMTP server. In the diagram below, Mail Manger is configured as an inbound SMTP Gateway:

Figure 1: Diagram of the inbound gateway mail flow to a mailbox hosting environment

Figure 1: Diagram of the inbound gateway mail flow to a mailbox hosting environment

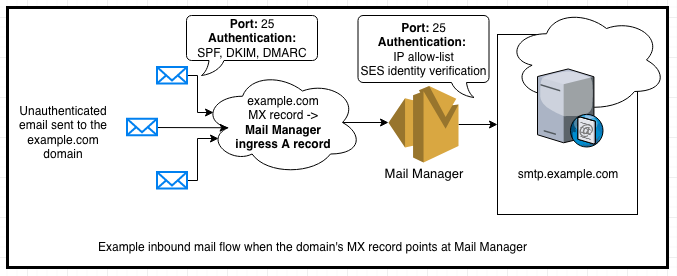
“Inbound email” refers to email traffic flows where the originator of the message can be either a trusted (for example: the UK division of Nutrition.co) or an untrusted (for example: a Nutrition.co customer or vendor) entity. To send an email, the originating email system looks up the recipient domain’s MX record in the global DNS system to determine the address for the recipient’s inbound mail server. Once a connection is established on port 25, the originating server delivers the email message using the SMTP protocol typically using STARTTLS for transport level encryption. Inbound messages are typically authenticated using the SPF, DKIM, and DMARC industry standard protocols, which help ensure the messages are coming from the legitimate sender’s domain.

An Inbound SMTP gateway can act on messages, for example to process and/or archive, before passing them along to the end recipient’s email server. To learn more about archiving emails in transit, visit this blog.

Configuring Mail Manager as an Inbound SMTP Gateway

Before we can configure Mail Manager as an Inbound Gateway for Nutrition.co’s Google Workspace and Microsoft 365 hosted mailboxes, we need to “allow-list” Mail Manager in Nutrition.co’s Google Workspace and Microsoft 365 settings. Allow-listing in this context refers to configuring the hosted mailbox environments such that Mail Manager is not identified as the source of messages, but rather as an SMTP relay.

This configuration is necessary because the messages being relayed through Mail Manager originate from both trusted and untrusted senders. This mail flow will contain both wanted and, potentially, unwanted messages. Mail Manager is the intermediary, not the source of potentially unwanted email passing through Mail Manager’s Open Ingress Point before being relayed to the destination mailbox environment.

If Mail Manager is not allow-listed, inbound email that is relayed thru Mail Manager’s Open Ingress Point will fail SPF checks because the IP addresses of the intermediary server are not authorized by the domain’s SPF policy. Since DMARC relies on SPF, messages from intermediary mail servers will fail the domain’s DMARC policy if they are not signed with a domain-aligned DKIM signature.

Mailbox hosting environments and their anti-spam algorithms rely on SPF, DKIM and DMARC for authenticating different inbound mail flow configurations before making an assessment about the message’s disposition. Properly authenticated messages, if not otherwise identified as unwanted by recipients and their security administrator, are delivered to Inboxes. Messages that are not authenticated are more likely to be treated as spam. Messages from intermediary servers can sometimes be mistaken as spoofed or unwanted messages.

By allow-listing the egress IP addresses of the Mail Manager servers, Nutrition.co’s Google Workspace and Microsoft 365 hosting environments will be able to assess the correct SPF result when receiving inbound email from Mail Manager.

Note: Do not include Mail Manager’s IP addresses in the domain’s SPF policy, These IP addresses are shared by other Mail Manager customers so including them in the domain’s SPF policy can introduce a security risk.

Note: It is also possible to use DKIM and ARC for allow-listing mail streams, but Gmail and Exchange Online both support IP allow-listing.

Note: Nutrition.co’s Google Workspace and Microsoft 365 hosting environments may still make a spam assessment about the messages under the context that Mail Manager is not the original sender, but this is not common.

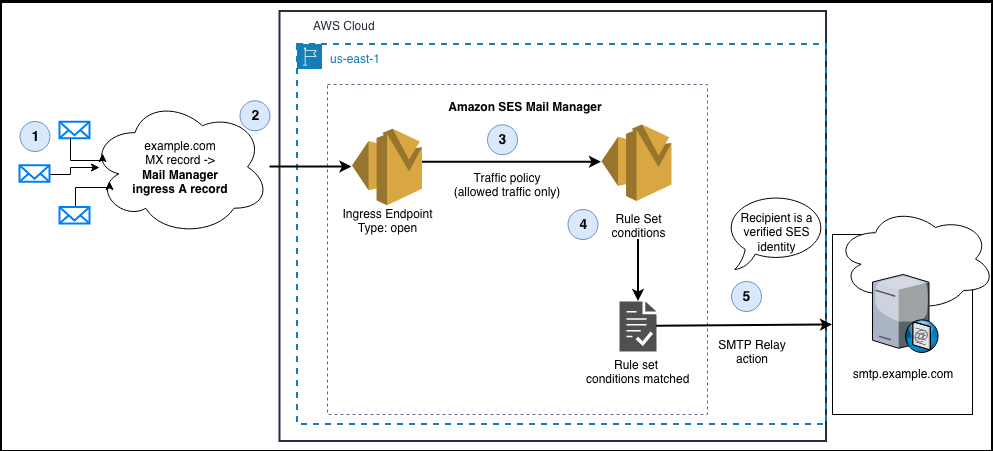
Figure 2: Diagram of the SES Mail Manager architecture to accept inbound email via an open Ingress endpoint and configured with a Rule set condition to relay messages with the SMTP Relay action.

Figure 2: Diagram of the SES Mail Manager architecture to accept inbound email via an open Ingress endpoint and configured with a Rule set condition to relay messages with the SMTP Relay action.

In the diagram above, the interaction points are as follows:

1. Email senders look in DNS to discover the MX record for example.com.
2. The value of the domain’s MX record is the A record of the Mail Manager Ingress endpoint. The Ingress endpoint is configured as an ‘open’ Ingress endpoint so that it can receive inbound email without requiring SMTP Auth
3. The Ingress endpoint traffic policy is configured to allow and deny traffic
4. The Rule Set conditions determine which messages are to be relayed
5. The SMTP Relay action relays messages for recipients that are SES verified identities

Configuring Mail Manager as an Inbound SMTP Gateway

Prerequisites

  • Access to the administrative console for Nutrition.co’s Google Workspace and Microsoft 365 hosted mailboxes
  • Access to the DNS zone hosting the MX records for the Nutrition.co’s domains

Step 1: Allow-list the regional Mail Manager IP addresses in Nutrition.co’s Google Workspace and Microsoft 365, and create the Mail Manager relay action(s) in AWS SES console.

  • If you do not configure the allow-list Nutrition.co’s Google Workspace and Microsoft 365 hosted, it may cause those mailbox providers to reject as spam or send to junk the emails replayed from your Mail Manager environment.

Step 1-a: Follow the instructions to allow-list Mail Manager to relay email to Nutrition.co’s Google Workspace and Microsoft 365 environments.

Step1-b: Create an SMTP relay for your mailbox hosting environment

* See Creating an SMTP relay in the SES console

Figure 3: Screenshot of an SMTP Relay rule action configured for Microsoft 365 Exchange Online inbound receiving

Figure 3: Screenshot of an SMTP Relay rule action configured for Microsoft 365 Exchange Online inbound receiving

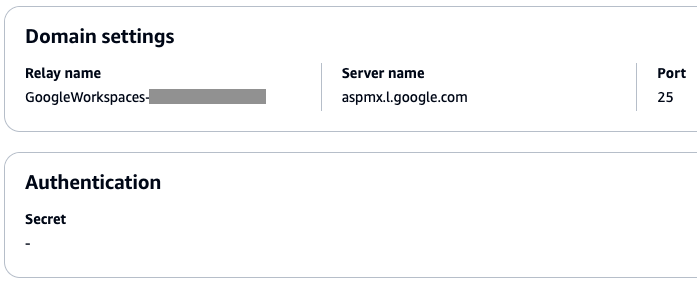
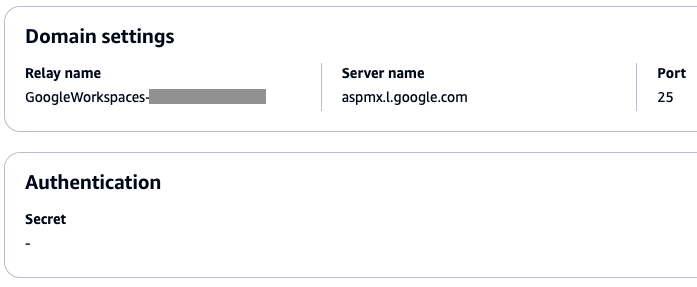
Figure 4: Screenshot of an SMTP Relay rule action configured for Google Workspaces Gmail inbound receiving

Figure 4: Screenshot of an SMTP Relay rule action configured for Google Workspaces Gmail inbound receiving

Because Nutrition.co hosts email in both Google Workspace and Microsoft 365, we must create SMTP Relay actions for both.

Step 2: In SES console, verify Nutrition.co’s email domain, which is nutrition.co

SES needs to prove that Nutrition.co owns the domain of each of the recipient addresses before it will begin relaying inbound email. If you cannot verify ownership of the recipient email destinations, SES will not relay messages.

Follow the instructions to verify Nutrition.co’s SES domain identity for the recipient email addresses within Nutrition.co’s Google Workspace and Microsoft 365 environments. (*note that subdomains such as customer-support.nutrition.co inherit verification from the parent domain*).

Figure 5: Screenshot of a successfully verified domain in the SES console.

Figure 5: Screenshot of a successfully verified domain in the SES console.

Step 3: Configure Mail Manager with an Open Ingress Point and Rule Set Action to relay inbound email to the mailbox hosting environment.

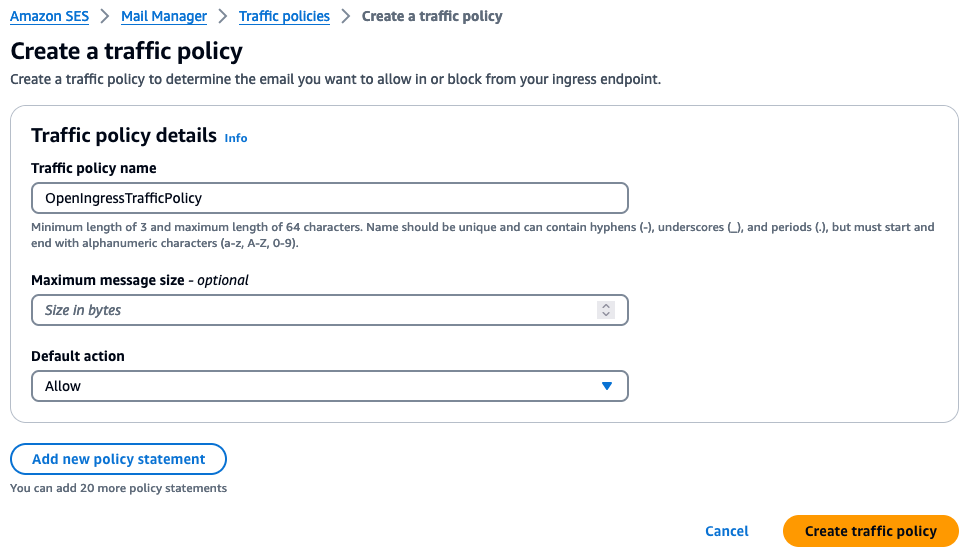
Step 3-a: See Create a Traffic Policy to accept inbound email from the internet.

  • Default action: Allow
    (Optional) Add Policy statements, depending on your requirements. Choose the action to be taken when the filter conditions are met: Deny

    • While Nutrition.co does not want to apply additional security via the SMTP Relay gateway, Mail Manager supports both native capabilities and optional add-on subscriptions to 3rd party tools from vetted industry leaders such as Spamhaus and Abusix.
Figure 6: Screenshot of a traffic policy for accepting all email from the internet

Figure 6: Screenshot of a traffic policy for accepting all email from the internet

Step 3-b: Follow the instructions for creating rule sets and rules in the SES console.

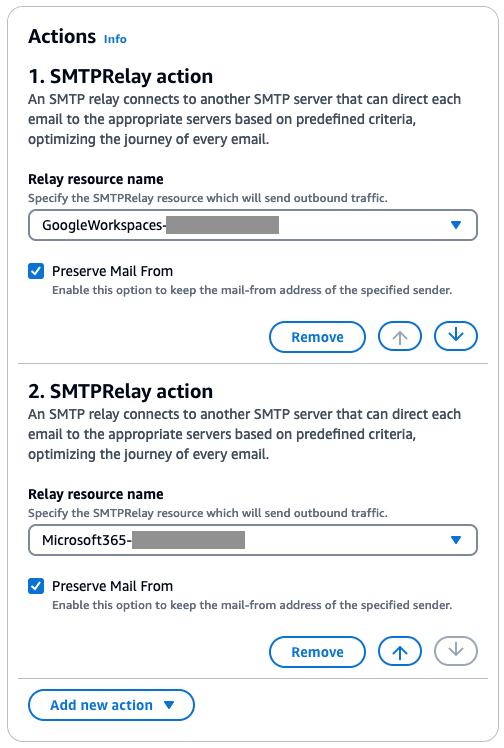
  • Select the SMTP Relay that you created in Step 1-b and enable the **Preserve Mail From** option.
    • The ‘Preserve Mail From’ setting is necessary so that the mailbox provider can be configured to make the correct assessment of the message’s SPF policy evaluation, assuming that the allow-list configuration Step 1 is complete.
  • Add any conditions and exceptions for each rule, depending on your needs.
    • You may want to create a condition for the SMTP Relay rule so that only messages destined for recipients within your domain are relayed to the appropriate SMTP Relay action, and choose a different action for the recipients who are not hosted in your environment, such as the Archive action.
    • If you have both Google Workspace and Microsoft 365 configured as SMTP Relay destinations, you may combine the SMTP Relay actions in a single rule if the conditions are the same, or create them as separate rules if the conditions need to be different
Figure 7: A Mail Manager rule configured with an SMTP Relay action for Google Workspaces and another SMTP Relay actions for Microsoft 365

Figure 7: A Mail Manager rule configured with an SMTP Relay action for Google Workspaces and another SMTP Relay actions for Microsoft 365

Step 3-c: Follow the documentation for Creating an Ingress Point.

The Mail Manager Ingress point needs to be ‘Open“ for this use case because internet mail senders need to connect to port 25 and send without SMTP authentication for inbound mail flows.

  • Type: Open
    Traffic policy: Choose the traffic policy that you created step 3-a
    Rule set: Choose the rule set that you created in step 3-b

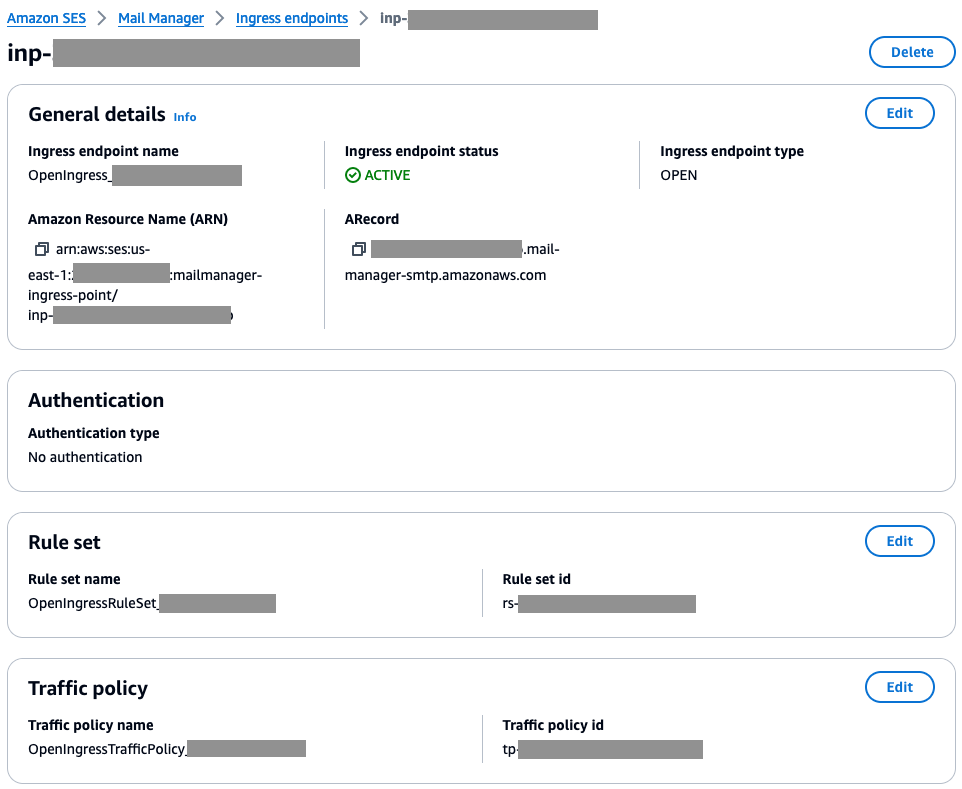
After saving the ingress endpoint settings, you should see something similar in the console.

Figure 8: Screenshot of an ‘open’ Mail Manager Ingress endpoint configured with a rule set and traffic policy

Figure 8: Screenshot of an ‘open’ Mail Manager Ingress endpoint configured with a rule set and traffic policy

Step 4. Verify your configuration and change your domain’s MX record

Once you have finished configuring Mail Manager with an Inbound Gateway configuration you will have:

  • An Open ingress point that does not require authentication and has an open traffic policy to allow messages from the internet.
  • A Rule set with SMTP Relay actions that will relay inbound messages to Google Workspace and/or Microsoft 365.

Step 4-a: Test your configuration

  • Ingress point: You can test that the Ingress endpoint receives email by using an SMTP capable client application, such as “openssl s_client” from a host that allows for outbound port 25 connections to the A Record of your Open Ingress Point (many ISPs and cloud infrastructure providers block port 25 by default to stop the proliferation of spam on the internet). If you get a “250 OK” response from the SMTP transaction, the Ingress point is configured correctly.
  • Rule set: You can test your Rule set by sending a message to your Ingress endpoint that has a recipient destination that is both a verified domain, and a domain that is hosted by your mailbox environment. You may want to add the Archive and/or Save to S3 rule actions to occur prior to SMTP Relay. This enables you to view message headers and diagnose issues that may occur during the SMTP relay to the mailbox hosting environments.
  • Final delivery: You can test the entire mail flow by looking at the received messages in your mailbox hosting environment.
    • How to look at received messages in a mailbox hosting environment
      • Google Workspace – From within the Gmail interface, find the message and open the message menu options.
      • Figure 9: Screenshot of Gmail’s interface for selecting message options
      • Choose “Show original”.
      • Screenshot of Gmail’s “Original message” summary showing SPF and DKIM passing and aligned with gmail.com, which was the source of the original message
      • Screenshot of the Gmail ‘Show original“ message headers. The Mail From address (also appears as the Return-path header, and envelope-from value in other headers) is preserved within the @gmail.com domain, and Gmail’s assessment of SPF correctly attributed the message as originating from 209.85.216.51 even though the message was relayed through 206.55.129.47. Since the 209.x.x.x address is in the SPF policy for gmail.com, the message passes SPF due to the allow-list configuration
      • (The Screenshot above shows the Gmail ‘Show original“ message headers. The Mail From address (also appears as the Return-path header, and envelope-from value in other headers) is preserved within the @gmail.com domain, and Gmail’s assessment of SPF correctly attributed the message as originating from 209.85.216.51 even though the message was relayed through 206.55.129.47. Since the 209.x.x.x address is in the SPF policy for gmail.com, the message passes SPF due to the allow-list configuration)
      • Microsoft 365 – From within the Outlook on the Web interface, find the message and open the message menu options.
      • Screenshot of Outlook on the Web’s interface for selecting message options
      • Choose “View message details”. You will see the message headers similar to the Gmail example above.

Step 4-b: Change the MX record for your domain.

Note: We recommend using a new subdomain so that you can test this mail flow configuration for a period of time prior to changing the MX record for the primary domain that is actively being used by end users and applications.

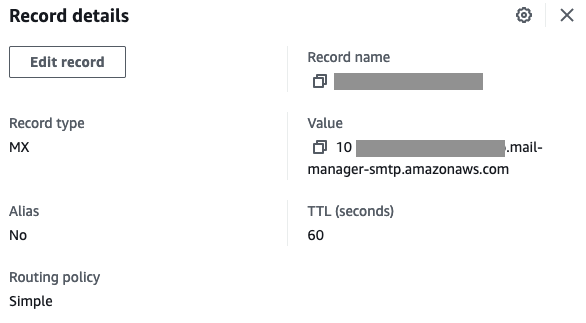
Once you have finished testing, you can change the MX record for the domain. The value of the MX record should be the **A Record** of the Open Ingress point along with the priority value.

Figure 13: A screenshot of an MX record configured in Amazon Route 53

Figure 13: A screenshot of an MX record configured in Amazon Route 53

Conclusion

In this blog post, we’ve explored how to leverage SES Mail Manager’s SMTP Relay action to simplify the handling of inbound email for organizations that use a mix of email hosting environments, specifically Google Workspace and Microsoft 365. By configuring Mail Manager as an inbound SMTP gateway, our fictitious customer, Nutrition.co was able to centralize the management of their email flows, enhance security through features like traffic policies and rule sets, and ensure compliance through flexible archiving.

The key steps involved setting up allow-listing in the Google Workspace and Microsoft 365 environments, creating SMTP relay configurations in Mail Manager, and updating Nutrition.co domain’s MX record to point to the Mail Manager ingress endpoint. This allowed Nutrition.co to seamlessly route inbound emails destined for both their cloud-hosted employee mailboxes and on-premises applications, processing and archiving the messages before final delivery.

The flexibility of Mail Manager’s SMTP Relay action makes it a powerful tool for organizations looking to unify their email infrastructure, especially in hybrid environments. By acting as a centralized ingress and egress gateway, Mail Manager can help streamline email management, improve security, and unlock new cloud-enabled email use cases. As email continues to be a critical communication channel, solutions like Mail Manager will become increasingly important for businesses looking to maximize the value of their email ecosystem.

Please visit AWS Re:Post to ask and find answers to questions about SES Mail Manager. Talk with your AWS account team if you are interested in exploring Mail Manager in more depth.

Additional blogs related to Mail Manager:

About the Authors

Jesse Thompson
Jesse Thompson is an Email Deliverability Manager with the Amazon Simple Email Service team. His background is in enterprise development and operations, with a focus on email abuse mitigation and encouragement of authenticity practices with open standard protocols. Jesse’s favorite activity outside of technology is recreational curling.
Alexey Kurbatsky

Alexey Kurbatsky

Alexey is a Senior Software Development Engineer at AWS, specializing in building distributed and scalable services. Outside of work, he enjoys exploring nature thru hiking as well as playing guitar.

Zip

Zip

Zip is a Sr. Specialist Solutions Architect at AWS, working with Amazon Pinpoint and Simple Email Service and WorkMail. Outside of work he enjoys time with his family, cooking, mountain biking, boating, learning and beach plogging.