Tag Archives: Uncategorized

Model Extraction from Neural Networks

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/model-extraction-from-neural-networks.html

A new paper, “Polynomial Time Cryptanalytic Extraction of Neural Network Models,” by Adi Shamir and others, uses ideas from differential cryptanalysis to extract the weights inside a neural network using specific queries and their results. This is much more theoretical than practical, but it’s a really interesting result.

Abstract:

Billions of dollars and countless GPU hours are currently spent on training Deep Neural Networks (DNNs) for a variety of tasks. Thus, it is essential to determine the difficulty of extracting all the parameters of such neural networks when given access to their black-box implementations. Many versions of this problem have been studied over the last 30 years, and the best current attack on ReLU-based deep neural networks was presented at Crypto’20 by Carlini, Jagielski, and Mironov. It resembles a differential chosen plaintext attack on a cryptosystem, which has a secret key embedded in its black-box implementation and requires a polynomial number of queries but an exponential amount of time (as a function of the number of neurons). In this paper, we improve this attack by developing several new techniques that enable us to extract with arbitrarily high precision all the real-valued parameters of a ReLU-based DNN using a polynomial number of queries and a polynomial amount of time. We demonstrate its practical efficiency by applying it to a full-sized neural network for classifying the CIFAR10 dataset, which has 3072 inputs, 8 hidden layers with 256 neurons each, and about 1.2 million neuronal parameters. An attack following the approach by Carlini et al. requires an exhaustive search over 2^256 possibilities. Our attack replaces this with our new techniques, which require only 30 minutes on a 256-core computer.

The US Is Banning Kaspersky

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/06/the-us-is-banning-kaspersky.html

This move has been coming for a long time.

The Biden administration on Thursday said it’s banning the company from selling its products to new US-based customers starting on July 20, with the company only allowed to provide software updates to existing customers through September 29. The ban—­the first such action under authorities given to the Commerce Department in 2019­—follows years of warnings from the US intelligence community about Kaspersky being a national security threat because Moscow could allegedly commandeer its all-seeing antivirus software to spy on its customers.

Best practices working with self-hosted GitHub Action runners at scale on AWS

Post Syndicated from Shilpa Sharma original https://aws.amazon.com/blogs/devops/best-practices-working-with-self-hosted-github-action-runners-at-scale-on-aws/

Overview

GitHub Actions is a continuous integration and continuous deployment platform that enables the automation of build, test and deployment activities for your workload. GitHub Self-Hosted Runners provide a flexible and customizable option to run your GitHub Action pipelines. These runners allow you to run your builds on your own infrastructure, giving you control over the environment in which your code is built, tested, and deployed. This reduces your security risk and costs, and gives you the ability to use specific tools and technologies that may not be available in GitHub hosted runners. In this blog, I explore security, performance and cost best practices to take into consideration when deploying GitHub Self-Hosted Runners to your AWS environment.

Best Practices

Understand your security responsibilities

GitHub Self-hosted runners, by design, execute code defined within a GitHub repository, either through the workflow scripts or through the repository build process. You must understand that the security of your AWS runner execution environments are dependent upon the security of your GitHub implementation. Whilst a complete overview of GitHub security is outside the scope of this blog, I recommended that before you begin integrating your GitHub environment with your AWS environment, you review and understand at least the following GitHub security configurations.

  • Federate your GitHub users, and manage the lifecycle of identities through a directory.
  • Limit administrative privileges of GitHub repositories, and restrict who is able to administer permissions, write to repositories, modify repository configurations or install GitHub Apps.
  • Limit control over GitHub Actions runner registration and group settings
  • Limit control over GitHub workflows, and follow GitHub’s recommendations on using third-party actions
  • Do not allow public repositories access to self-hosted runners

Reduce security risk with short-lived AWS credentials

Make use of short-lived credentials wherever you can. They expire by default within 1 hour, and you do not need to rotate or explicitly revoke them. Short lived credentials are created by the AWS Security Token Service (STS). If you use federation to access your AWS account, assume roles, or use Amazon EC2 instance profiles and Amazon ECS task roles, you are using STS already!

In almost all cases, you do not need long-lived AWS Identity and Access Management (IAM) credentials (access keys) even for services that do not “run” on AWS – you can extend IAM roles to workloads outside of AWS without requiring you to manage long-term credentials. With GitHub Actions, we suggest you use OpenID Connect (OIDC). OIDC is a decentralized authentication protocol that is natively supported by STS using sts:AssumeRoleWithWebIdentity, GitHub and many other providers. With OIDC, you can create least-privilege IAM roles tied to individual GitHub repositories and their respective actions. GitHub Actions exposes an OIDC provider to each action run that you can utilize for this purpose.

Short lived AWS credentials with GitHub self-hosted runners

Short lived AWS credentials with GitHub self-hosted runners

If you have many repositories that you wish to grant an individual role to, you may run into a hard limit of the number of IAM roles in a single account. While I advocate solving this problem with a multi-account strategy, you can alternatively scale this approach by:

  • using attribute based access control (ABAC) to match claims in the GitHub token (such as repository name, branch, or team) to the AWS resource tags.
  • using role based access control (RBAC) by logically grouping the repositories in GitHub into Teams or applications to create fewer subset of roles.
  • use an identity broker pattern to vend credentials dynamically based on the identity provided to the GitHub workflow.

Use Ephemeral Runners

Configure your GitHub Action runners to run in “ephemeral” mode, which creates (and destroys) individual short-lived compute environments per job on demand. The short environment lifespan and per-build isolation reduces the risk of data leakage , even in multi-tenanted continuous integration environments, as each build job remains isolated from others on the underlying host.

As each job runs on a new environment created on demand, there is no need for a job to wait for an idle runner, simplifying auto-scaling. With the ability to scale runners on demand, you do not need to worry about turning build infrastructure off when it is not needed (for example out of office hours), giving you a cost-efficient setup. To optimize the setup further, consider allowing developers to tag workflows with instance type tags and launch specific instance types that are optimal for respective workflows.

There are a few considerations to take into account when using ephemeral runners:

  • A job will remain queued until the runner EC2 instance has launched and is ready. This can take up to 2 minutes to complete. To speed up this process, consider using an optimized AMI with all prerequisites installed.
  • Since each job is launched on a fresh runner, utilizing caching on the runner is not possible. For example, Docker images and libraries will always be pulled from source.

Use Runner Groups to isolate your runners based on security requirements

By using ephemeral runners in a single GitHub runner group, you are creating a pool of resources in the same AWS account that are used by all repositories sharing this runner group. Your organizational security requirements may dictate that your execution environments must be isolated further, such as by repository or by environment (such as dev, test, prod).

Runner groups allow you to define the runners that will execute your workflows on a repository-by-repository basis. Creating multiple runner groups not only allow you to provide different types of compute environments, but allow you to place your workflow executions in locations within AWS that are isolated from each other. For example, you may choose to locate your development workflows in one runner group and test workflows in another, with each ephemeral runner group being deployed to a different AWS account.

Runners by definition execute code on behalf of your GitHub users. At a minimum, I recommend that your ephemeral runner groups are contained within their own AWS account and that this AWS account has minimal access to other organizational resources. When access to organizational resources is required, this can be given on a repository-by-repository basis through IAM role assumption with OIDC, and these roles can be given least-privilege access to the resources they require.

Optimize runner start up time using Amazon EC2 warm-pools

Ephemeral runners provide strong build isolation, simplicity and security. Since the runners are launched on demand, the job will be required to wait for the runner to launch and register itself with GitHub. While this usually happens in under 2 minutes, this wait time might not be acceptable in some scenarios.

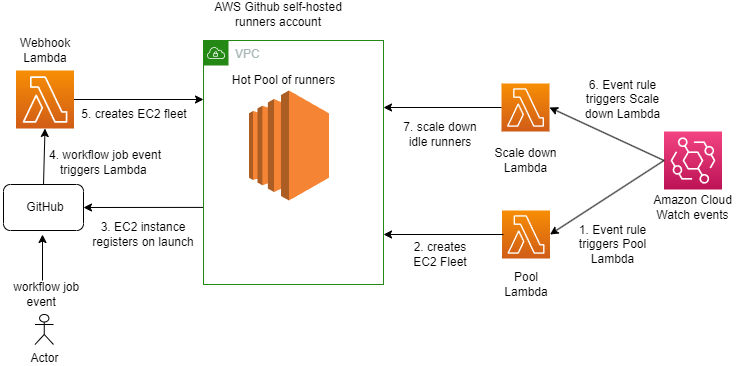
We can use a warm pool of pre-registered ephemeral runners to reduce the wait time. These runners will listen to the incoming GitHub workflow events actively and as soon as an incoming workflow event is queued, it is picked up readily by the warm pool of registered EC2 runners.

While there can be multiple strategies to manage the warm pool, I recommend the following strategy which uses AWS Lambda for scaling up and scaling down the ephemeral runners:

GitHub self-hosted runners warm pool flow

GitHub self-hosted runners warm pool flow

A GitHub workflow event is created on a trigger like push of code in a master repository or a merge of pull request. This event triggers a Lambda function via webhook and Amazon API Gateway endpoint. The Lambda function helps in validating the GitHub workflow event payload and log events for observability & building metrics. It can be used optionally to replenish the warm pool. There are separate backend Lambda functions to launch, scale up and scale down the warm pool of EC2 instances. The EC2 instances or runners are registered with GitHub at the time of launch. The registered runners listens for incoming GitHub work flow events using GitHub’s internal job queue and as soon as workflow events are triggered, its assigned by GitHub to one of the runners in warm pool for job execution. The runner is automatically de-registered once the job completes. A job can be a build, or deploy request as defined in your GitHub workflow.

With warm pool in place, it is expected to help reduce wait time by 70-80%.

Considerations

  • Increased complexity as there is a possibility of over provisioning runners. This will depend on how long a runner EC2 instance requires to launch and reach a ready state and how frequently the scale up Lambda is configured to run. For example, if the scale up Lambda runs every 1 minute and the EC2 runner requires 2 minutes to launch, then the scale up Lambda will launch 2 instances. The mitigation is to use Auto scaling groups to manage the EC2 warm pool and desired capacity with predictive scaling policies tying back to incoming GitHub workflow events i.e. build job requests.
  • This strategy may have to be revised when supporting Windows or Mac based runners given the spin up times can vary.

Use an optimized AMI to speed up the launch of GitHub self-hosted runners

Amazon Machine Images (AMI) provide a pre-configured, optimized image that can be used to launch the runner EC2 instance. By using AMIs, you will be able to reduce the launch time of a new runner since dependencies and tools are already installed. Consistency across builds is guaranteed due to all instances running the same version of dependencies and tools. Runners will benefit from increased stability and security compliance as images are tested and approved before being distributed for use as runner instances.

When building an AMI for use as a GitHub self-hosted runner the following considerations need to be made:

  • Choosing the right OS base image for the builds. This will depend on your tech stack and toolset.
  • Install the GitHub runner app as part of the image. Ensure automatic runner updates are enabled to reduce the overhead of managing running versions. In case a specific runner version must be used you can disable automatic runner updates to avoid untested changes. Keep in mind, if disabled, a runner will need to be updated manually within 30 days of a new version becoming available.
  • Install build tools and dependencies from trusted sources.
  • Ensure runner logs are captured and forwarded to your security information and event management (SIEM) of choice.
  • The runner requires internet connectivity to access GitHub. This may require configuring proxy settings on the instance depending on your networking setup.
  • Configure any artifact repositories the runner requires. This includes sources and authentication.
  • Automate the creation of the AMI using tools such as EC2 Image Builder to achieve consistency.

Use Spot instances to save costs

The cost associated with scaling up the runners as well as maintaining a hot pool can be minimized using Spot Instances, which can result in savings up to 90% compared to On-Demand prices. However, there could be requirements where we can have longer running builds or batch jobs that cannot tolerate the spot instance terminating on 2 minutes notice. So, having a mixed pool of instances will be a good option where such jobs should be routed to on-demand EC2 instances and the rest on the Spot instances to cater for diverse build needs. This can be done by assigning labels to the runner during launch /registration. In that case, the on-demand instances will be launched and we can a savings plan in place to get cost benefits.

Record runner metrics using Amazon CloudWatch for Observability

It is vital for the observability of the overall platform to generate metrics for the EC2 based GitHub self-hosted runners. Examples of the GitHub runners metrics can be: the number of GitHub workflow events queued or completed in a minute, or number of EC2 runners up and available in the warm pool etc.

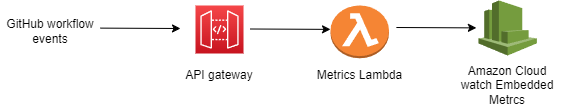
We can log the triggered workflow events and runner logs in Amazon CloudWatch and then use CloudWatch embedded metrics to collect metrics such as number of workflow events queued, in progress and completed. Using elements like “started_at” and “completed_at” timings which are part of workflow event payload we can calculate build wait time.

As an example, below is the sample incoming GitHub workflow event logged in Amazon Cloud Watch Logs

<p> </p><p><code>{</code></p><p><code>"hostname": "xxx.xxx.xxx.xxx",</code></p><p><code>"requestId": "aafddsd55-fgcf555",</code></p><p><code>"date": "2022-10-11T05:50:35.816Z",</code></p><p><code>"logLevel": "info",</code></p><p><code>"logLevelId": 3,</code></p><p><code>"filePath": "index.js",</code></p><p><code>"fullFilePath": "/var/task/index.js",</code></p><p><code>"fileNa<a class="ab-item" href="https://aws-blogs-prod.amazon.com/devops/" aria-haspopup="true">AWS DevOps Blog</a>me": "index.js",</code></p><p><code>"lineNumber": 83889,</code></p><p><code>"columnNumber": 12,</code></p><p><code>"isConstructor": false,</code></p><p><code>"functionName": "handle",</code></p><p><code>"argumentsArray": [</code></p><p><code>"Processing Github event",</code></p><p><code>"{\"event\":\"workflow_job\",\"repository\":\"testorg-poc/github-actions-test-repo\",\"action\":\"queued\",\"name\":\"jobname-buildanddeploy\",\"status\":\"queued\",\"started_at\":\"2022-10-11T05:50:33Z\",\"completed_at\":null,\"conclusion\":null}"</code></p><p><code>]</code></p><p><code>}</code></p>

In order to use the logged elements of above log into metrics by capturing \”status\”:\”queued\”,\”repository\”:\”testorg-poc/github-actions-test-repo\c, \”name\”:\”jobname-buildanddeploy\” ,and workflow \”event\” , one can build embedded metrics in the application code or AWS metrics Lambda using any of the cloud watch metrics client library Creating logs in embedded metric format using the client libraries – Amazon CloudWatch based on the language of your choice listed.c

Essentially what one of those libraries will do under the hood is map elements from Log event into dimension fields so cloud watch can then read and generate a metric using that.

console.log(<br />      JSON.stringify({<br />        message: '[Embedded Metric]', // Identifier for metric logs in CW logs<br />        build_event_metric: 1, // Metric Name and value<br />        status: `${status}`, // Dimension name and value<br />        eventName: `${eventName}`,<br />        repository: `${repository}`,<br />        name: `${name}`,<br />        <br />        _aws: {<br />          Timestamp: Date.now(),<br />          CloudWatchMetrics: [<br />            {<br />              Namespace: `demo_2`,<br />              Dimensions: [['status','eventName','repository','name']],<br />              Metrics: [<br />                {<br />                  Name: 'build_event_metric',<br />                  Unit: 'Count',<br />                },<br />              ],<br />            },<br />          ],<br />        },<br />      })<br />    );

A sample architecture:

Consumption of GitHub webhook events

Consumption of GitHub webhook events

The cloud watch metrics can be published to your dashboards or forwarded to any external tool based on requirements. Once we have metrics, CloudWatch alarms and notifications can be configured to manage pool exhaustion.

Conclusion

In this blog post, we outlined several best practices covering security, scalability and cost efficiency when using GitHub Actions with EC2 self-hosted runners on AWS. We covered how using short-lived credentials combined with ephemeral runners will reduce security and build contamination risks. We also showed how runners can be optimized for faster startup and job execution AMIs and warm EC2 pools. Last but not least, cost efficiencies can be maximized by using Spot instances for runners in the right scenarios.

Resources:

How to use Mail Manager to Archive Inbound Emails

Post Syndicated from Sesan Komaiya original https://aws.amazon.com/blogs/messaging-and-targeting/archiving-and-sending-to-final-smtp-server/

In today’s digital landscape, where email communication plays a vital role in business operations, Keeping your email archive secure, compliant, and retrievable is crucial for any business. However, managing the large volume of email data can lead to operational difficulties, including regulatory compliance, maintaining an audit trail, and preventing data loss. That’s where Amazon Simple Email Service (SES) Mail Manager’s email archiving feature comes in.

In this blog post, we will explore how Amazon SES Mail Manager’s email archiving and search features can improve email security and compliance. If you’re a newcomer to Mail Manager, look at this blog post on Amazon SES Mail Manager. It provides valuable information on important features, such as Ingress Endpoint, Traffic Policy, Rule Sets, and SMTP Relay.

Problem Statement:

Imagine a scenario where a critical email from a key client is buried deep within your organization’s email archives, and you need to retrieve it for an important audit. The challenge of ensuring your business remains compliant with stringent data retention policies across every email communication for thousands of employees for a certain period or permanently.

Solution explained:

Amazon SES Mail Manager Email archiving is a powerful tool that addresses many of the challenges organizations face dealing with the difficulty and expense of archiving email at scale. Compliance and regulatory frameworks like GDPR, HIPAA, and SOX often require email archiving, which is a common objective identified by customers needing to comply with those regulatory frameworks. For regulated businesses, failure to comply with email archiving regulations can result in severe financial penalties and reputational damage.

Amazon SES Mail Manager securely archives and safeguards your emails, providing easy search and export functionality. It provides full-time, enterprise-level archiving without increasing the storage requirements of your mailbox server. The feature provides a reliable and efficient solution to address most compliance requirements. By automatically archiving the types of emails you specify, the service ensures that your organization maintains a comprehensive audit trail of its communications, enabling quick retrieval and review as needed.

The email archiving feature of Mail Manager provides organizations the ability to archive email while in transit rather than archiving at the user’s mailbox. Many organizations prefer archiving in transit for email archiving to meet compliance requirements and maintain comprehensive records. If you would like to learn more about in transit archiving, visit this blog –  Email Archiving with Mail Manager: Why To Archive In Transit vs At The Mailbox.

How email flows with an Amazon SES Mail Manager Email Archiving

For instructional purposes in this blog post, we’ll focus on how you can introduce Mail Manager archiving into your existing email infrastructure. We’ll cover how to seamlessly integrate Mail Manager with reference architectures. Later in the blog, we are going to explore Mail Manager’s archiving capabilities, including search, export and retention policies.

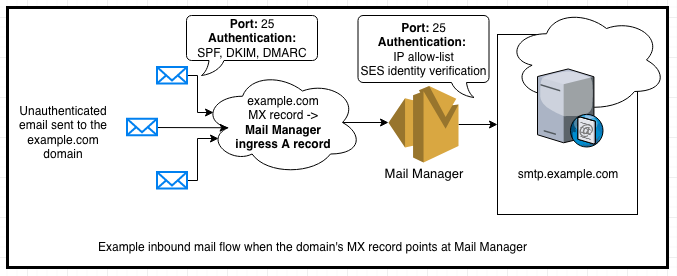
Current setup

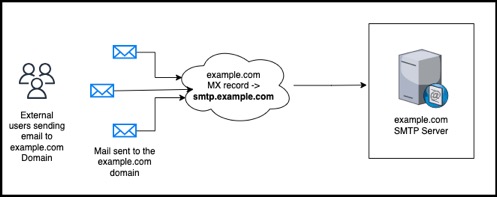
Our example organization has an existing mail server (it might be a on-premises Microsoft Exchange Server, Microsoft 365, Google Workspace, etc). Their DNS is configured to route all email directly to this mail server. There is currently no archiving capacity within the existing email infrastructure, when needed, archiving is handled by individual mailbox users and PST files. While this method is suitable for personal email archiving, it fails to meet the organizations’ security requirements and compliance standards.

Figure 1: Example organization’s existing inbound email workflow.

Email Archiving in transit

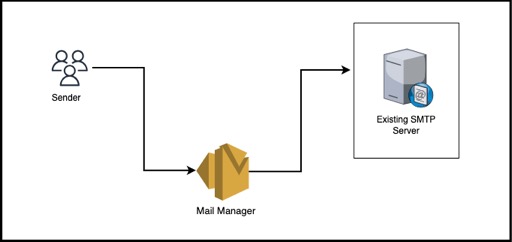
We are going to introduce Mail Manager into the current mail flow (see figure 1) to archive all incoming messages from our example enterprise’s email infrastructure.

Figure 2: Example organization’s proposed inbound email workflow, with Mail Manager archiving in-transit prior to delivery.

In the new architecture (see figure 2), we’ve introduced Mail Manager into the organization’s inbound email workflow. This new workflow leverages Mail Manager’s ability to archive either all inbound emails, or only those that match specified criteria. By using a Mail Manager Rule set, our example organization can selectively store and preserve emails that meet their configured criteria.

Mail Manager Email Archiving and Search and Export Capabilities

Mail Manager’s archive search capabilities are designed to be user-friendly and efficient. You can perform searches based on various criteria, such as sender, recipient, subject line, date range, or even specific keywords in the Subject line. The search results provide options to either export the search to Amazon Simple Storage Service (S3), or you can choose to download a single email.

Let’s explore using Mail Manager’s archive search to find a specific email by the sender’s address:

Figure 3: Mail Manager’s archive search interface

Once found, we can click on the results to review the email in the console:

Figure 4: Mail Manager’s archive search results

Once we’ve found the target email, it can be downloaded by clicking on “View details“. The image below shows an example message details page with information about the email, including message headers such as In-Reply-To, X-Original-Mailer and X-Mailer.

Figure 5: Mail Manager’s archived email detailed page

Mail Manager’s archive search history tab allows us to find archive searches created in the last 30 days, and view the search results, as shown in the image below:

Figure 6: Mail Manager’s archive search history

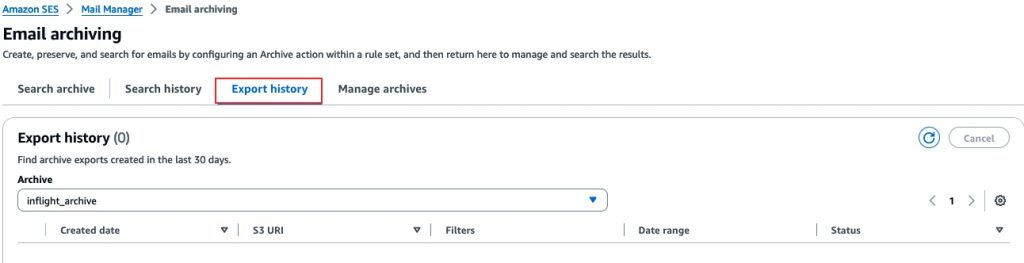
Mail Manager’s archive export history tab lists all of the archived email searches you exported to an Amazon S3 Bucket within the last 30 days.

Figure 7: Export History

Step by Step Setup:

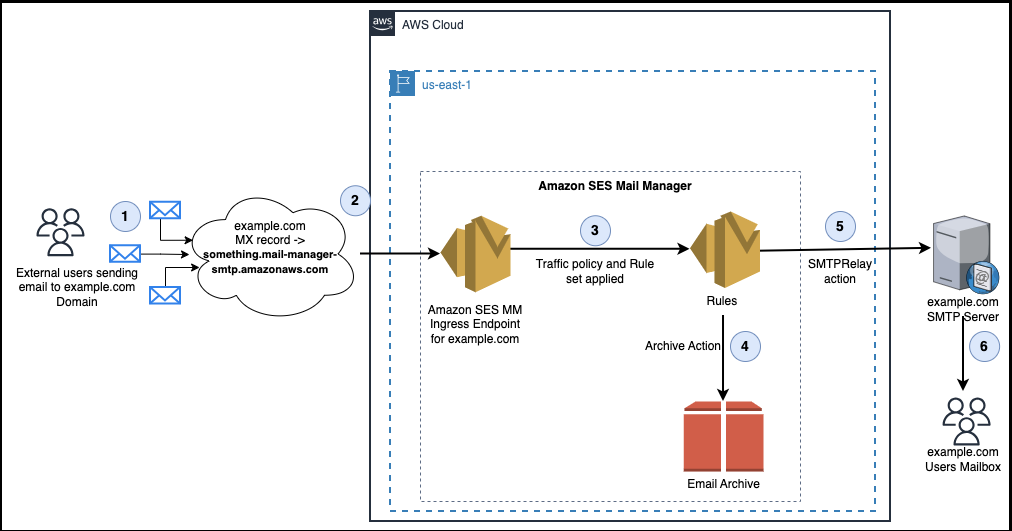
Now that we have explained how Mail Manger can be inserted into our example organization’s email workflow to provide email archiving, let’s explore how you can implement Mail Manager’s archiving capabilities in your inbound email workflows. The following diagram (Figure 3) illustrates the overall structure and components involved in this architecture:

Figure 8: End-to-End Mail workflow

Follow the steps below to configure Mail Manager in your AWS account to implement this architecture:

  1. Log into the SES Console and select Mal Manager from the left navigation menu.
    1. Note, as of this writing, Mail Manager is generally available in the following AWS Regions: US East (N. Virginia), US West (Oregon), Europe (Ireland, Frankfurt), Asia Pacific (Tokyo, Sydney).
  2. Under Mail Manger navigation, create an archive (or multiple archives for different use cases)
    1. Enter a unique name in the Archive name field.
    2. (Optional) Select a retention period in the Retention period field to override the default retention period of 180 days.
    3. (Optional) You can encrypt your archive either by entering your own AWS KMS key into the KMS key ARN field, or by selecting Create new key.
    4. Choose Create archive.
  3. Under Mail Manger navigation, create a traffic policy to determine the email you want to block or allow.
    1. Create traffic policy.
    2. On the Create a traffic policy page, enter a unique name for your traffic policy.
    3. (Optional) If you want to discard any messages above a certain size, enter a value in bytes in the Maximum message size field.
    4. In Default action, choose whether the traffic policy is to either Allow or Deny (block) messages that fall outside of (are not addressed by) the conditions of your policy statements.
    5. Select Add new policy statement to create a statement for your traffic policy.
    6. Choose either Allow or Deny (block) for the action to be taken when the statement’s conditions are met.
    7. Build a condition by selecting an email protocol and a conditional operator for the value you enter. Select Add new condition if you want to add more conditions to this policy statement. To learn more about a condition property and its operators and valid values, see the Policy statement conditions reference.
    8. If you’re subscribed to an Email Add On, you’ll be able to select it here as an email protocol.
    9. If you want add more policy statements and conditions, repeat steps above.
    10. Select Create traffic policy.
  4. Under Mail Manger navigation, create a rule set to perform actions on the email you allow in.
    1. Create rule set and enter a unique name for your rule set.
    2. Create new rule on the edit page.
    3. In the Rule details sidebar, enter a unique name for your rule.
    4. Select Add new condition to create a condition that the message must match; or check the EXCEPT in the case of: box followed by Add new exception to create a condition that the message must not match.
    5. Build the condition or exception by selecting an email property and a conditional operator for the value you enter. Select Add new condition or Add new exception if you want to add more conditions or exceptions to this rule. To learn more about a condition property and its operators and valid values, see the Rule conditions reference.
    6. Select Add new action to define the action to be taken when the rule’s conditions are matched and/or exceptions are not matched. To add more actions to be taken, select Add new action. To learn more about actions and their parameters, see the Rule actions reference.
    7. Create an Archive rule. Save rule set
  5. Under Mail Manger navigation, Create your ingress endpoint and assign to it the traffic policy and rule set.
    1. choose Ingress endpoints under Mail Manager.
    2. On the Ingress endpoints page, select Create ingress endpoint.
    3. On the Create new ingress endpoint page, enter a unique name for your ingress endpoint.
    4. Choose whether it will be a Open or Authenticated endpoint.
    5. Select a traffic policy to determine the email you want to block or allow.
    6. Select a rule set containing the rule actions you want to perform on the email you allow in.
    7. Select Create ingress endpoint.
  6. Configure your environment to use the ingress endpoint.
    1. At the time you create an ingress endpoint, an “A” record for the endpoint will be generated and its value displayed on the ingress endpoint’s summary screen in the SES console. The way you use the value of this record depends on the type of endpoint you created and your use case.
    2. DNS providers have different procedures and interfaces for configuring email records. The key pieces of information you need to put into your DNS settings are listed in our documentation – https://docs.aws.amazon.com/ses/latest/dg/eb-ingress.html#eb-ingress-a-record
  7. Under Mail Manger navigation, create an SMTP Relay to send mail on to your existing mail server.
    1. choose SMTP relays under Mail Manager.
    2. On the SMTP relays page, select Create SMTP relay.
    3. On the Create SMTP relay page, enter a unique name for your SMTP relay.
    4. Depending on what type of SMTP Realy you want to configure, follow the respective instructions:
      1. inbound (non-authenticated)
      2. outbound (authenticated) SMTP relay
  8. Update your DNS MX records to point to your new Mail Manager’s ingress point, instead of the existing mail server.

Note: Make sure that you have tested the steps above in your development environment and that you understand the steps before deploying into your production environment.

Conclusion

Amazon SES Mail Manager’s email archiving capabilities are designed for organizations that are seeking to enhance the security, compliance, and audit-ability of their email communications. By seamlessly integrating this feature into their existing email infrastructure, organizations can now archive all inbound messages in transit, ensuring a comprehensive, tamper-proof record of their email activities. The powerful search and export functionality of Mail Manager makes it easy to quickly locate and access specific emails when needed, whether for compliance audits, legal requests, or internal investigations.

This level of email visibility and control is particularly crucial for organizations operating in highly regulated industries like government, healthcare and finance, where the stakes for non-compliance can be severe. Beyond the compliance benefits, Mail Manager’s email archiving also helps to alleviate the operational headaches and expenses associated with traditional in-house archiving systems. By offloading this responsibility to AWS, organizations can focus their resources on their core business priorities, while still maintaining the security and accessibility of their critical email data.

If you’re looking to strengthen your email security posture, simplify your compliance efforts, and improve the overall management of your email archives, we encourage you to explore how Amazon SES Mail Manager’s email archiving capabilities can be seamlessly integrated into your existing email infrastructure. Take the first step towards a more secure, compliant, and efficient email management solution by contacting us today.

About the Authors

Sesan Komaiya

Sesan Komaiya

Sesan is a Solutions Architect at Amazon Web Services. He works with a variety of customers, helping them with cloud adoption, cost optimization and emerging technologies. Sesan has over 15 year’s experience in Enterprise IT and has been at AWS for 5 years. In his free time, Sesan enjoys watching various sporting activities like Soccer, Tennis and Moto sport. He has 2 kids that also keeps him busy at home.

Alexey Kurbatsky

Alexey Kurbatsky

Alexey is a Senior Software Development Engineer at AWS, specializing in building distributed and scalable services. Outside of work, he enjoys exploring nature thru hiking as well as playing guitar.

Jesse Thompson
Jesse Thompson is an Email Deliverability Manager with the Amazon Simple Email Service team. His background is in enterprise development and operations, with a focus on email abuse mitigation and encouragement of authenticity practices with open standard protocols. Jesse’s favorite activity outside of technology is recreational curling.
Zip

Zip

Zip is a Sr. Specialist Solutions Architect at AWS, working with Amazon Pinpoint and Simple Email Service and WorkMail. Outside of work he enjoys time with his family, cooking, mountain biking, boating, learning and beach plogging.

How to use SES Mail Manager SMTP Relay action to deliver inbound email to Google Workspace and Microsoft 365

Post Syndicated from Zip Zieper original https://aws.amazon.com/blogs/messaging-and-targeting/how-to-use-ses-mail-manager-smtp-relay-action-to-deliver-inbound-email-to-google-workspace-and-microsoft-365/

Introduction

Customers often ask us if the Amazon Simple Email Service (SES) inbound capabilities they use with applications hosted on AWS infrastructure can also be used to process and automate employee email hosted on public services like Google Workspace and Microsoft 365. The answer has typically been “yes, but with some limitations”, as until now, SES inbound has been somewhat constrained by the fact that it didn’t support relaying messages for an existing domain. This limitation makes it very difficult to fully manage email flows across hybrid email environments.

Such conversations led the SES team to create Amazon Simple Email Service (SES) Mail Manager which offers a set of capabilities that simplify managing large volumes of email communications within an organization. Mail Manager’s rules set conditions and actions can optimize routing for improved delivery and communication flow, both for incoming and outgoing emails. Mail Manager’s email security features can be augmented by optional add-ons from industry-leading, vetted third-party providers. Flexible archiving features help organizations meet stringent compliance and record-keeping requirements.

In this blog, we position Mail Manager as a central ingress gateway for a fictitious company, Nutrition.co, that is based on real-world AWS customers. We discuss the customer challenges and explain how to configure Mail Manager’s SMTP Relay action to intercept, archive then deliver emails destined for employees’ Google Workspace hosted Gmail and Microsoft 365 hosted Exchange Online mailboxes. Similar mail flows can be used to process, automate and archive emails destined for their AWS hosted apps.

You can learn more about all of Mail Manager’s capabilities here.

Customer background and use case

Our fictitious company, Nutrition.co, is an online retail business with multiple employee departments, including administration, marketing, sales and fulfillment. The company has acquired several smaller rivals that use both Google Workspace and Microsoft 365 to host their employee inboxes, and plan to consolidate all users onto the same domain ( such as [email protected] and [email protected]). They also host several applications on Amazon Web Services (AWS) that use Amazon SES’ inbound capability to receive emails using a subdomain *customer-support*.nutrition.co, such as orders@*customer-support*.nutrition.co and returns@*customer-support*.nutrition.co.

Nutrition.co is looking for a solution to unify all their email domain routing, security and archiving processes onto one centralized management system to simplify their email infrastructure. They want an approach that provides more flexibility to control which addresses and domains are used for apps and automation as well as employee mail. They also want to enhance email compliance and governance with a flexible solution for screening, processing and archiving inbound emails to both employees and applications, before delivering those emails to recipient inboxes on Google Workspace and Microsoft 365 and applications hosted on AWS.

The SES Mail Manger based central ingress and egress gateway architecture we propose will allow Nutrition.co to manage their peer-to-peer and application-driven emails in one place, Amazon SES. It will simplify email security and management, and make it easy to unlock new cloud-enabled email use cases. The architecture can be modified to acommodate a wide variety of email infrastructure, including fully cloud hosted, on-premises, and hybrid mailbox hosting environments.

What is an Inbound SMTP Gateway?

An Inbound SMTP Gateway is an SMTP server that accepts inbound email via an Open Ingress Point, and then delivers those messages to another email environment’s inbound SMTP server. In the diagram below, Mail Manger is configured as an inbound SMTP Gateway:

Figure 1: Diagram of the inbound gateway mail flow to a mailbox hosting environment

Figure 1: Diagram of the inbound gateway mail flow to a mailbox hosting environment

“Inbound email” refers to email traffic flows where the originator of the message can be either a trusted (for example: the UK division of Nutrition.co) or an untrusted (for example: a Nutrition.co customer or vendor) entity. To send an email, the originating email system looks up the recipient domain’s MX record in the global DNS system to determine the address for the recipient’s inbound mail server. Once a connection is established on port 25, the originating server delivers the email message using the SMTP protocol typically using STARTTLS for transport level encryption. Inbound messages are typically authenticated using the SPF, DKIM, and DMARC industry standard protocols, which help ensure the messages are coming from the legitimate sender’s domain.

An Inbound SMTP gateway can act on messages, for example to process and/or archive, before passing them along to the end recipient’s email server. To learn more about archiving emails in transit, visit this blog.

Configuring Mail Manager as an Inbound SMTP Gateway

Before we can configure Mail Manager as an Inbound Gateway for Nutrition.co’s Google Workspace and Microsoft 365 hosted mailboxes, we need to “allow-list” Mail Manager in Nutrition.co’s Google Workspace and Microsoft 365 settings. Allow-listing in this context refers to configuring the hosted mailbox environments such that Mail Manager is not identified as the source of messages, but rather as an SMTP relay.

This configuration is necessary because the messages being relayed through Mail Manager originate from both trusted and untrusted senders. This mail flow will contain both wanted and, potentially, unwanted messages. Mail Manager is the intermediary, not the source of potentially unwanted email passing through Mail Manager’s Open Ingress Point before being relayed to the destination mailbox environment.

If Mail Manager is not allow-listed, inbound email that is relayed thru Mail Manager’s Open Ingress Point will fail SPF checks because the IP addresses of the intermediary server are not authorized by the domain’s SPF policy. Since DMARC relies on SPF, messages from intermediary mail servers will fail the domain’s DMARC policy if they are not signed with a domain-aligned DKIM signature.

Mailbox hosting environments and their anti-spam algorithms rely on SPF, DKIM and DMARC for authenticating different inbound mail flow configurations before making an assessment about the message’s disposition. Properly authenticated messages, if not otherwise identified as unwanted by recipients and their security administrator, are delivered to Inboxes. Messages that are not authenticated are more likely to be treated as spam. Messages from intermediary servers can sometimes be mistaken as spoofed or unwanted messages.

By allow-listing the egress IP addresses of the Mail Manager servers, Nutrition.co’s Google Workspace and Microsoft 365 hosting environments will be able to assess the correct SPF result when receiving inbound email from Mail Manager.

Note: Do not include Mail Manager’s IP addresses in the domain’s SPF policy, These IP addresses are shared by other Mail Manager customers so including them in the domain’s SPF policy can introduce a security risk.

Note: It is also possible to use DKIM and ARC for allow-listing mail streams, but Gmail and Exchange Online both support IP allow-listing.

Note: Nutrition.co’s Google Workspace and Microsoft 365 hosting environments may still make a spam assessment about the messages under the context that Mail Manager is not the original sender, but this is not common.

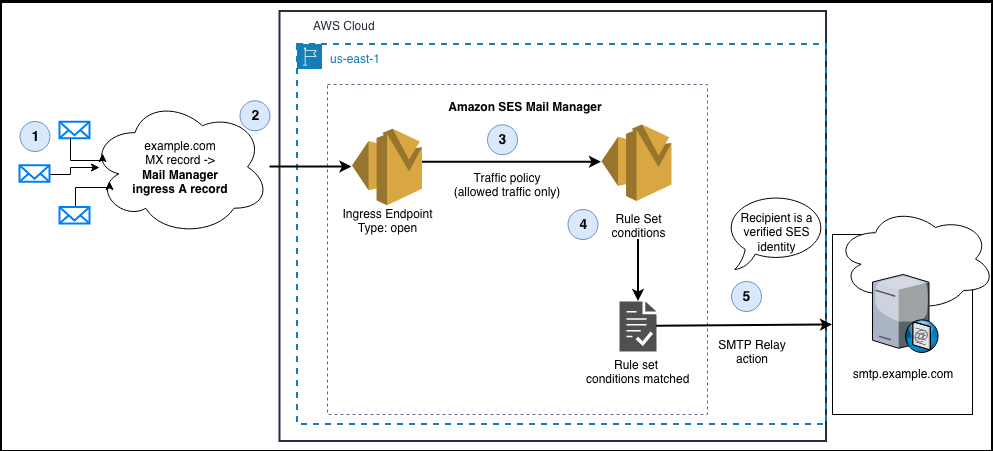
Figure 2: Diagram of the SES Mail Manager architecture to accept inbound email via an open Ingress endpoint and configured with a Rule set condition to relay messages with the SMTP Relay action.

Figure 2: Diagram of the SES Mail Manager architecture to accept inbound email via an open Ingress endpoint and configured with a Rule set condition to relay messages with the SMTP Relay action.

In the diagram above, the interaction points are as follows:

1. Email senders look in DNS to discover the MX record for example.com.
2. The value of the domain’s MX record is the A record of the Mail Manager Ingress endpoint. The Ingress endpoint is configured as an ‘open’ Ingress endpoint so that it can receive inbound email without requiring SMTP Auth
3. The Ingress endpoint traffic policy is configured to allow and deny traffic
4. The Rule Set conditions determine which messages are to be relayed
5. The SMTP Relay action relays messages for recipients that are SES verified identities

Configuring Mail Manager as an Inbound SMTP Gateway

Prerequisites

  • Access to the administrative console for Nutrition.co’s Google Workspace and Microsoft 365 hosted mailboxes
  • Access to the DNS zone hosting the MX records for the Nutrition.co’s domains

Step 1: Allow-list the regional Mail Manager IP addresses in Nutrition.co’s Google Workspace and Microsoft 365, and create the Mail Manager relay action(s) in AWS SES console.

  • If you do not configure the allow-list Nutrition.co’s Google Workspace and Microsoft 365 hosted, it may cause those mailbox providers to reject as spam or send to junk the emails replayed from your Mail Manager environment.

Step 1-a: Follow the instructions to allow-list Mail Manager to relay email to Nutrition.co’s Google Workspace and Microsoft 365 environments.

Step1-b: Create an SMTP relay for your mailbox hosting environment

* See Creating an SMTP relay in the SES console

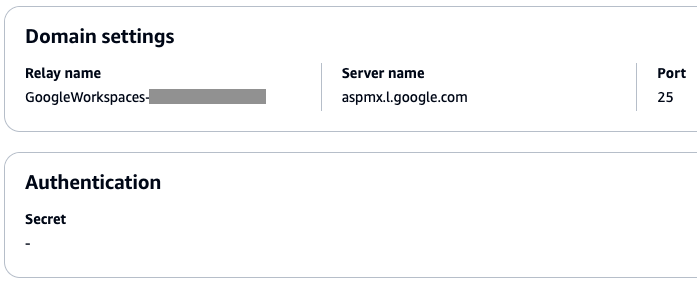
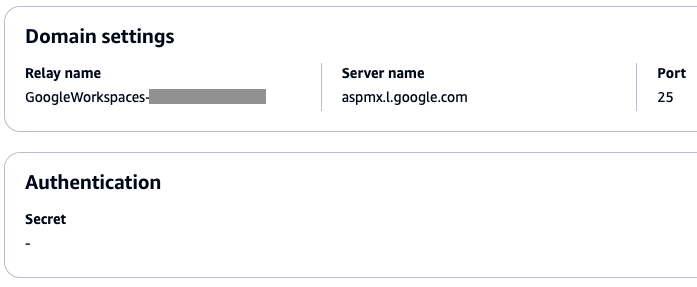
Figure 3: Screenshot of an SMTP Relay rule action configured for Microsoft 365 Exchange Online inbound receiving

Figure 3: Screenshot of an SMTP Relay rule action configured for Microsoft 365 Exchange Online inbound receiving

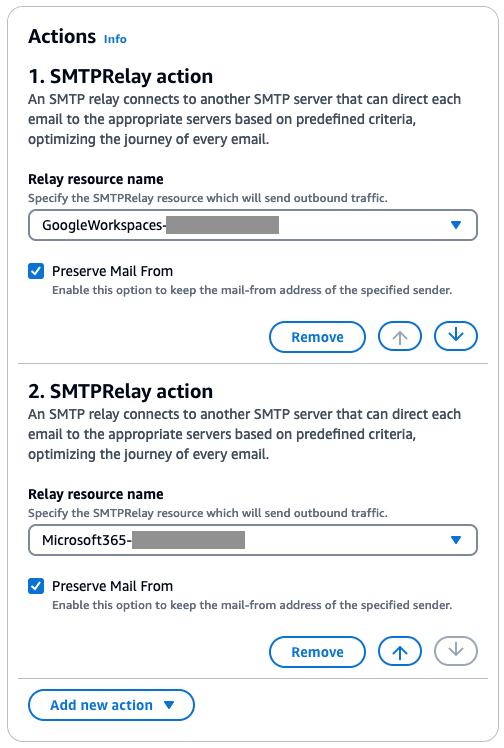
Figure 4: Screenshot of an SMTP Relay rule action configured for Google Workspaces Gmail inbound receiving

Figure 4: Screenshot of an SMTP Relay rule action configured for Google Workspaces Gmail inbound receiving

Because Nutrition.co hosts email in both Google Workspace and Microsoft 365, we must create SMTP Relay actions for both.

Step 2: In SES console, verify Nutrition.co’s email domain, which is nutrition.co

SES needs to prove that Nutrition.co owns the domain of each of the recipient addresses before it will begin relaying inbound email. If you cannot verify ownership of the recipient email destinations, SES will not relay messages.

Follow the instructions to verify Nutrition.co’s SES domain identity for the recipient email addresses within Nutrition.co’s Google Workspace and Microsoft 365 environments. (*note that subdomains such as customer-support.nutrition.co inherit verification from the parent domain*).

Figure 5: Screenshot of a successfully verified domain in the SES console.

Figure 5: Screenshot of a successfully verified domain in the SES console.

Step 3: Configure Mail Manager with an Open Ingress Point and Rule Set Action to relay inbound email to the mailbox hosting environment.

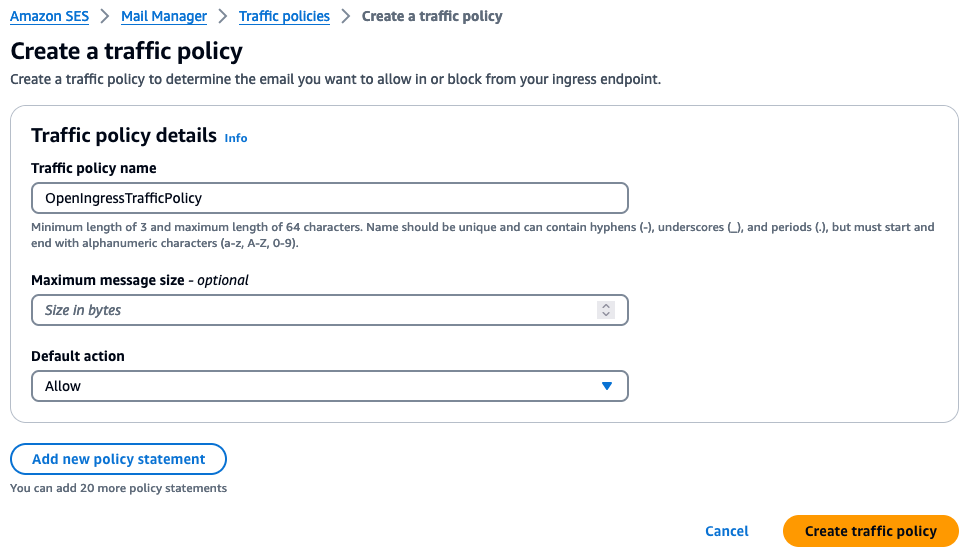
Step 3-a: See Create a Traffic Policy to accept inbound email from the internet.

  • Default action: Allow
    (Optional) Add Policy statements, depending on your requirements. Choose the action to be taken when the filter conditions are met: Deny

    • While Nutrition.co does not want to apply additional security via the SMTP Relay gateway, Mail Manager supports both native capabilities and optional add-on subscriptions to 3rd party tools from vetted industry leaders such as Spamhaus and Abusix.
Figure 6: Screenshot of a traffic policy for accepting all email from the internet

Figure 6: Screenshot of a traffic policy for accepting all email from the internet

Step 3-b: Follow the instructions for creating rule sets and rules in the SES console.

  • Select the SMTP Relay that you created in Step 1-b and enable the **Preserve Mail From** option.
    • The ‘Preserve Mail From’ setting is necessary so that the mailbox provider can be configured to make the correct assessment of the message’s SPF policy evaluation, assuming that the allow-list configuration Step 1 is complete.
  • Add any conditions and exceptions for each rule, depending on your needs.
    • You may want to create a condition for the SMTP Relay rule so that only messages destined for recipients within your domain are relayed to the appropriate SMTP Relay action, and choose a different action for the recipients who are not hosted in your environment, such as the Archive action.
    • If you have both Google Workspace and Microsoft 365 configured as SMTP Relay destinations, you may combine the SMTP Relay actions in a single rule if the conditions are the same, or create them as separate rules if the conditions need to be different
Figure 7: A Mail Manager rule configured with an SMTP Relay action for Google Workspaces and another SMTP Relay actions for Microsoft 365

Figure 7: A Mail Manager rule configured with an SMTP Relay action for Google Workspaces and another SMTP Relay actions for Microsoft 365

Step 3-c: Follow the documentation for Creating an Ingress Point.

The Mail Manager Ingress point needs to be ‘Open“ for this use case because internet mail senders need to connect to port 25 and send without SMTP authentication for inbound mail flows.

  • Type: Open
    Traffic policy: Choose the traffic policy that you created step 3-a
    Rule set: Choose the rule set that you created in step 3-b

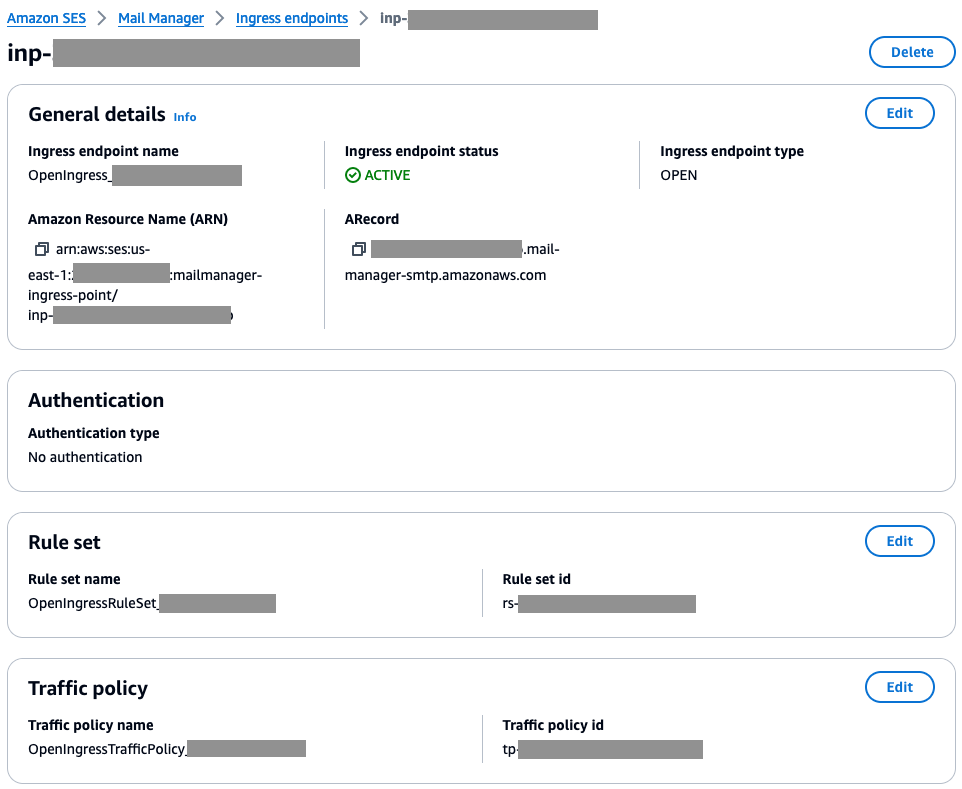
After saving the ingress endpoint settings, you should see something similar in the console.

Figure 8: Screenshot of an ‘open’ Mail Manager Ingress endpoint configured with a rule set and traffic policy

Figure 8: Screenshot of an ‘open’ Mail Manager Ingress endpoint configured with a rule set and traffic policy

Step 4. Verify your configuration and change your domain’s MX record

Once you have finished configuring Mail Manager with an Inbound Gateway configuration you will have:

  • An Open ingress point that does not require authentication and has an open traffic policy to allow messages from the internet.
  • A Rule set with SMTP Relay actions that will relay inbound messages to Google Workspace and/or Microsoft 365.

Step 4-a: Test your configuration

  • Ingress point: You can test that the Ingress endpoint receives email by using an SMTP capable client application, such as “openssl s_client” from a host that allows for outbound port 25 connections to the A Record of your Open Ingress Point (many ISPs and cloud infrastructure providers block port 25 by default to stop the proliferation of spam on the internet). If you get a “250 OK” response from the SMTP transaction, the Ingress point is configured correctly.
  • Rule set: You can test your Rule set by sending a message to your Ingress endpoint that has a recipient destination that is both a verified domain, and a domain that is hosted by your mailbox environment. You may want to add the Archive and/or Save to S3 rule actions to occur prior to SMTP Relay. This enables you to view message headers and diagnose issues that may occur during the SMTP relay to the mailbox hosting environments.
  • Final delivery: You can test the entire mail flow by looking at the received messages in your mailbox hosting environment.
    • How to look at received messages in a mailbox hosting environment
      • Google Workspace – From within the Gmail interface, find the message and open the message menu options.
      • Figure 9: Screenshot of Gmail’s interface for selecting message options
      • Choose “Show original”.
      • Screenshot of Gmail’s “Original message” summary showing SPF and DKIM passing and aligned with gmail.com, which was the source of the original message
      • Screenshot of the Gmail ‘Show original“ message headers. The Mail From address (also appears as the Return-path header, and envelope-from value in other headers) is preserved within the @gmail.com domain, and Gmail’s assessment of SPF correctly attributed the message as originating from 209.85.216.51 even though the message was relayed through 206.55.129.47. Since the 209.x.x.x address is in the SPF policy for gmail.com, the message passes SPF due to the allow-list configuration
      • (The Screenshot above shows the Gmail ‘Show original“ message headers. The Mail From address (also appears as the Return-path header, and envelope-from value in other headers) is preserved within the @gmail.com domain, and Gmail’s assessment of SPF correctly attributed the message as originating from 209.85.216.51 even though the message was relayed through 206.55.129.47. Since the 209.x.x.x address is in the SPF policy for gmail.com, the message passes SPF due to the allow-list configuration)
      • Microsoft 365 – From within the Outlook on the Web interface, find the message and open the message menu options.
      • Screenshot of Outlook on the Web’s interface for selecting message options
      • Choose “View message details”. You will see the message headers similar to the Gmail example above.

Step 4-b: Change the MX record for your domain.

Note: We recommend using a new subdomain so that you can test this mail flow configuration for a period of time prior to changing the MX record for the primary domain that is actively being used by end users and applications.

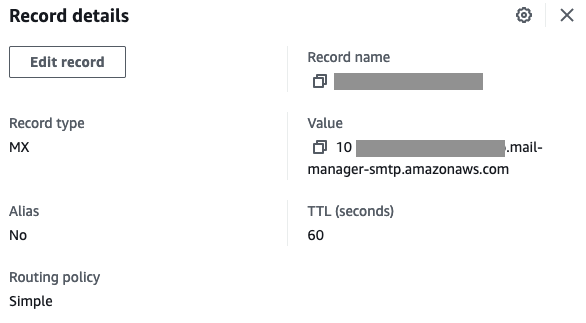
Once you have finished testing, you can change the MX record for the domain. The value of the MX record should be the **A Record** of the Open Ingress point along with the priority value.

Figure 13: A screenshot of an MX record configured in Amazon Route 53

Figure 13: A screenshot of an MX record configured in Amazon Route 53

Conclusion

In this blog post, we’ve explored how to leverage SES Mail Manager’s SMTP Relay action to simplify the handling of inbound email for organizations that use a mix of email hosting environments, specifically Google Workspace and Microsoft 365. By configuring Mail Manager as an inbound SMTP gateway, our fictitious customer, Nutrition.co was able to centralize the management of their email flows, enhance security through features like traffic policies and rule sets, and ensure compliance through flexible archiving.

The key steps involved setting up allow-listing in the Google Workspace and Microsoft 365 environments, creating SMTP relay configurations in Mail Manager, and updating Nutrition.co domain’s MX record to point to the Mail Manager ingress endpoint. This allowed Nutrition.co to seamlessly route inbound emails destined for both their cloud-hosted employee mailboxes and on-premises applications, processing and archiving the messages before final delivery.

The flexibility of Mail Manager’s SMTP Relay action makes it a powerful tool for organizations looking to unify their email infrastructure, especially in hybrid environments. By acting as a centralized ingress and egress gateway, Mail Manager can help streamline email management, improve security, and unlock new cloud-enabled email use cases. As email continues to be a critical communication channel, solutions like Mail Manager will become increasingly important for businesses looking to maximize the value of their email ecosystem.

Please visit AWS Re:Post to ask and find answers to questions about SES Mail Manager. Talk with your AWS account team if you are interested in exploring Mail Manager in more depth.

Additional blogs related to Mail Manager:

About the Authors

Jesse Thompson
Jesse Thompson is an Email Deliverability Manager with the Amazon Simple Email Service team. His background is in enterprise development and operations, with a focus on email abuse mitigation and encouragement of authenticity practices with open standard protocols. Jesse’s favorite activity outside of technology is recreational curling.
Alexey Kurbatsky

Alexey Kurbatsky

Alexey is a Senior Software Development Engineer at AWS, specializing in building distributed and scalable services. Outside of work, he enjoys exploring nature thru hiking as well as playing guitar.

Zip

Zip

Zip is a Sr. Specialist Solutions Architect at AWS, working with Amazon Pinpoint and Simple Email Service and WorkMail. Outside of work he enjoys time with his family, cooking, mountain biking, boating, learning and beach plogging.

Email Archiving with Mail Manager: Why To Archive In Transit vs At The Mailbox

Post Syndicated from Zip Zieper original https://aws.amazon.com/blogs/messaging-and-targeting/email-archiving-with-mail-manager-why-to-archive-in-transit-vs-at-the-mailbox/

When designing Amazon Simple Email Service’s (SES) Mail Manager, we often heard from customers about the “PST-file problem” inherent with user-side mailbox-based archiving. This occurs when, for a variety of reasons, end users decide to archive their emails to local PST files or other local storage. These PST files are fragile and easily corrupted. Furthermore, they are subject to the backup practices of individual workstations. Lastly, PST files are readily are portable and can be easily copied and moved outside the visibility of the email system and your IT and IP controls.

We developed Amazon Simple Email Service (SES) Mail Manager archiving features in response to this problem, and based on additional customer feedback: the need for consistent email retention behaviors, for all email. Customers also wanted the flexibility to determine which messages to archive, where to put them, and how long to retain those messages.

To make the feature applicable to the widest set of use cases, we designed Mail Manager to be able to archive any email traversing the SES service, not just those that have already been delivered to a user’s mailbox. This added flexibility ensures organizations can maintain a complete record of exactly those email communications they wish to preserve. Rather than require external tools to search and export Mail Manager’s archives, we built these functions directly into the SES console.

In fact, the entire Media Manager archiving solution is fully managed by SES within the customer’s Mail Manager account, reducing the operational overhead traditionally associated with email archiving and compliance.

Figure 1 - Mail Manager Archiving

Figure 1 – Mail Manager Archiving

At the core of the SES Mail Manager archiving solution is the ability to capture and retain any message, regardless of its source or destination, as it flows through the service’s rules engine. This design approach ensures that every email message traversing Mail Manager can be subject to archiving and retention policies, rather than requiring organizations to manage different systems and tools for mail flowing through mail servers, internal relays and other email infrastructure. The result is a unified, comprehensive compliance solution that provides visibility and control over an organization’s email archiving.

SES also published a detailed overview of the Archiving feature, which is available here: Archiving and sending to final SMTP server.

Archiving on its own isn’t an innovation; it’s an email primitive – an essential capability that can be used to enable other, more complex solutions. Historically, retention of email was configured as a function of your on-premises mail server, where your mailboxes themselves were resident. Personally-authored emails were considered the high-value material to retain, and adding archiving as a function of mailbox configurations was the simplest approach.

In practice, we find that the mail captured at the mailbox server, or end user’s inbox, represents only a fraction of of the mail a typical enterprise generates. As organizations grow, the number of applications generating Application To Person (A2P) messages tends to increase dramatically. Similarly, as corporate environments become more complex, SaaS-based solutions that are external to the primary email infrastructure often use email to update employees along with workflow-management systems. Much of that mail eludes archiving as it bypasses individual user mailboxes.

The SES strategy for archiving is to capture mail from anywhere, to anywhere, as long as it transits an ingress endpoint as part of your Mail Manager configuration. You have two choices: you can write those messages directly to an S3 bucket you control, and then ingest it into any other tool you like. Alternately, you can send messages into a managed archive within Mail Manager, and gain access to search, export, and configurable retention features. By default, SES configures retention for 6 months, but it’s adjustable up to permanent retention for customers who require it.

Mail Manager’s archiving feature captures any message which matches your rule, or all messages traversing any ingress endpoint. You can choose to write all messages to or from your senior leadership team into one archive, or you can organize by other envelope metadata. The rules operate the same way whether the message is A2P or Person to Person (P2P), ensuring uniform policies and retention options.

With Mail Manager’s managed archives, you pay for each gigabyte ingested, indexed, and available for search, and a separate storage fee for each gigabyte retained every month. Note that the storage fee includes both the raw content of the messages, and the size of the computed index required for search and export functions.

For messages you write to your S3 buckets, you also have the option to invoke an S3 trigger action that calls an Amazon Lambda to drive various automatation workflows. Regulated industries might want to write all messages to S3 to leverage S3’s glacier storage option for very long-term storage.

You can even split your workload between Mail Manager’s managed archive, for emails you are likely to need readily discoverable, and the Write to S3 option, for content which you don’t expect to ever need to search with granularity, but still needs to be archived to “check the box” for your retention policy. In fact, AWS encourages such a builder-oriented approach, because it rewards thoughtful decisions and resource utilization, and conforms to the broad goal of consumption-based pricing, which Mail Manager embraces fully at every step.

Figure 2 - Rule Set with conditions for archiving

Figure 2 – Rule Set with conditions for archivingMail Manager provides a more comprehensive, resilient archiving approach that increases both the overall scope of mail that can be captured, and the fidelity of the archived data. You don’t need any special adapters or plugins to capture mail from any source. All email that comes through your Mail Manager Ingress Endpoint can be archived.

Figure 3 - Create archive

Figure 3 – Create archive

Why not try Mail Manager today and experience the benefits of a centralized, scalable email archiving solution? You’ll pay only for the data you ingest and retain each month, without the fragility and visibility issues of user-managed archives. Visit the SES website to start your free trial of Mail Manager and take control of your organization’s critical email records. To start with Mail Manager, visit https://aws.amazon.com/ses/, click on Mail Manager, and set up your first workload today.

If you have any questions or need further guidance, feel free to reach out to us via the SES Forums or in the comments section of this blog post. We’re here to help you navigate the evolving email landscape and unlock the full potential of your Amazon SES investment.

About the Authors

Toby Weir-Jones

Toby Weir-Jones

Toby is a Principal Product Manager for Amazon SES and WorkMail. He joined AWS in January 2021 and has significant experience in both business and consumer information security products and services. His focus on email solutions at SES is all about tackling a product that everyone uses and finding ways to bring innovation and improved performance to one of the most ubiquitous IT tools.

Brett Ezell

Brett Ezell

Brett is an Amazon Pinpoint and Amazon Simple Email Service Specialist Solutions Architect at AWS. As a Navy veteran, he joined AWS in 2020 through an AWS technical military apprenticeship program. When he isn’t deep diving into solutions for customer challenges, Brett spends his time collecting vinyl, attending live music, and training at the gym. An admitted comic book nerd, he feeds his addiction every Wednesday by combing through his local shop for new books.

Zip

Zip

Zip is a Sr. Specialist Solutions Architect at AWS, working with Amazon Pinpoint and Simple Email Service and WorkMail. Outside of work he enjoys time with his family, cooking, mountain biking, boating, learning and beach plogging.

Five ways Amazon Q simplifies AWS CloudFormation development

Post Syndicated from Ryan Kiel original https://aws.amazon.com/blogs/devops/five-ways-amazon-q-simplifies-aws-cloudformation-development/

Introduction

As a builder, AWS CloudFormation provides a reliable way for you to model, provision, and manage AWS and third-party resources by treating infrastructure as code. First-time and experienced users of CloudFormation can often encounter some challenges when it comes to development of templates and stacks. CloudFormation offers a vast library of over 1,250 resource types covering AWS services, and supports numerous features and functionalities in both the construction of a template, as well as the deployment of a stack using that template. The broad array of options at one’s disposal provides a broad landscape to navigate.

In 2023, AWS introduced a new generative AI-powered assistant, Amazon Q. Amazon Q is the most capable generative AI-powered assistant for accelerating software development and leveraging companies’ internal data. Amazon Q Developer can answer questions about AWS architecture, best practices, documentation, support, and more. When used in an integrated development environment (IDE), Amazon Q Developer additionally provides software development assistance, including code explanation, code generation, and code improvements such as debugging and optimization.

In this blog post, we will show you five ways Amazon Q Developer can help you work with CloudFormation for template code generation, querying CloudFormation resource requirements, explaining existing template code, understanding deployment options and issues, and querying CloudFormation documentation.

Prerequisites

Amazon Q can be interacted with in different ways. The first way is native integration within the AWS Console. When logged into the console, you will see a “Q” logo. Click on it to open a chat window, and then you can begin asking questions to Amazon Q without any setup.

You can also interact with Amazon Q Developer after following these instructions to set it up in your Interactive Development Environment (IDE).

1. Template Code Generation

The foundational element of any CloudFormation stack begins with a template that describes your infrastructure as code, in either a JSON or YML format. The anatomy of what comprises a stack can be found here. Creating a template requires knowledge of the template format, as well as the proper structure of each CloudFormation resource that you include in the ‘Resources’ section.

With Amazon Q, you can generate a template from natural language without having to look up the particular definition of each resource.

Template code Generation using Amazon Q

Figure 1: Template code Generation using Amazon Q

In Figure 1 above, I asked Amazon Q if it could provide me with a CloudFormation template with Lambda code in python to list all EBS volumes in a region. It generated sample code that provides the minimum template I would need to create it. It also added the IAM role needed to execute the Lambda code. Finally, it included documentation links that can be reference for further usage.

With a single message to Amazon Q, I am off and running in seconds, ready to deploy my first CloudFormation stack.

2. Understanding CloudFormation Resource Properties

Another area where Q can help if you are already familiar with the structure of a resource, is by informing you of resource properties and their significance.

In the next use case, I encountered an issue with my template where certain properties were missing that are required for the resource. With Amazon Q, I can quickly understand the required property, and what it defines for my resource.

Stack Events & Q information on Required Parameters

Stack Events & Q information on Required Parameters

Figure 2: Stack Events & Q information on Required Parameters

Since the CloudFormation Events tab indicated that the error was a missing resource property, I asked Amazon Q to help me understand why the property was required, and what it defines. Now, without having to dig through documentation, I can make sure that my template code includes DefaultCacheBehavior and what that will define for my resource.

3. Explaining Existing Template Code

A benefit of Amazon CloudFormation and Infrastructure as Code is that templates allow developers to share and distribute both snippets and entire stacks as pre-defined JSON or YML files. Template reusability can help with the development of new systems, or the augmentation of existing ones – without needing to do any of the template development yourself.

In this example, I have borrowed a template snippet from the AWS documentation for a DynamoDB table. I have copied and pasted this template into my IDE.

In my IDE, I have integrated Amazon Q. As shown in Figure 3, I can highlight a specified section of my template code, and then ask Amazon Q to explain what it is doing for us.

Explaining CloudFormation code by Amazon Q

Figure 3: Explaining CloudFormation code by Amazon Q

After asking Amazon Q to ‘Explain selected code’, I am given a detailed description of my highlighted template snippet. Q tells me that this is an Auto Scaling policy for a DynamoDB Table write capacity. It informs me what resource type it is (AWS::ApplicationAutoScaling::ScalingPolicy), and also describes what the function of that resource is, in the context of my DynamoDB Table. Next, it gives me detailed bullet points explaining all of the parameters of the resource definition, and how that impacts my table as well. It then concludes with a summary of the highlighted code that is easily digestible and understandable to the reader, and even offers to provide more information if needed.

In just one simple question to Amazon Q, I have quickly gone from copy and pasting existing code to now understanding its usage and functionality.

4. Understanding Deployment Issues

Sometimes developers may encounter issues when creating, updating or deleting CloudFormation stacks. When you come across errors with your AWS CloudFormation stack, you can ask Amazon Q to help you find the source of the problems.

Reasoning stack failures by Amazon Q
Figure 4: Reasoning stack failures by Amazon Q

Amazon Q answered why my CloudFormation stack failed to deploy and gave me different ways to check and fix the issues before trying again.

5. Querying CloudFormation Documentation & Functionality

Sometimes developers need to query CloudFormation documentation and functionality to build templates for their use case. Amazon Q can help with these requests straight from IDE. One such example is where developers ask Amazon Q to explain how to make sure my database is not deleted when a CloudFormation stack is deleted. In Figure 5, Amazon Q recommends few ways to make sure the RDS database is not deleted.

Query Amazon Q for CloudFormation documentation

Figure 5: Query Amazon Q for CloudFormation documentation

Sometimes developers need deploy the CloudFormation stack across regions and accounts which can be achieved by using StackSets. In the following example, I asked it for help to understand this feature.

Query Amazon Q for CloudFormation StackSets functionality
Figure 6: Query Amazon Q for CloudFormation StackSets functionality

It is also possible to ask Amazon Q for help with the prompts themselves. In the example below, I ask it to provide some hints on what kinds of questions I could ask about CloudFormation.
CloudFormation functionality prompts

Figure 7: CloudFormation functionality prompts

In the example below, I ask one of those questions to dive into stack dependencies.

CloudFormation stack dependencies
Figure 8: CloudFormation stack dependencies

Conclusion

Utilizing Amazon Q allows developers and builders to be more efficient. As a builder you can use Amazon Q in your IDE to create CloudFormation templates and improve existing CloudFormation templates. If you have inherited an existing CloudFormation template, you can use Amazon Q to understand it. Reducing template and stack development time is one exciting way that Amazon Q and Generative AI are enabling customers to move faster.

Ryan Kiel

Ryan Kiel

Ryan Kiel is a Senior Solutions Architect for AWS based out of Virginia. As part of AWS Sports, he helps leagues and franchises with their cloud journey on AWS by leveraging best practices and the newest technology. Outside of work, Ryan is a hockey, golf, and motorsports enthusiast.

Aneesh Varghese

Aneesh Varghese

Aneesh Varghese is a Senior Technical Account Manager at AWS with more than 17 years of Information Technology industry experience. Aneesh supports enterprise customers in cost optimization strategies, providing advocacy and strategic technical guidance to help plan and build solutions using AWS best practices. Outside of work, Aneesh likes to spend time with family, play Basketball and Badminton.

Karthik Chemudupati

Karthik Chemudupati

Karthik Chemudupati is a Principal Technical Account Manager (TAM) with AWS, focused on helping customers achieve cost optimization and operational excellence. He has 20 years of IT experience in software engineering, cloud operations and automations. Karthik joined AWS in 2016 as a TAM and worked with more than dozen Enterprise Customers across US-West. Outside of work, he enjoys spending time with his family.

Recovering Public Keys from Signatures

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/06/recovering-public-keys-from-signatures.html

Interesting summary of various ways to derive the public key from digitally signed files.

Normally, with a signature scheme, you have the public key and want to know whether a given signature is valid. But what if we instead have a message and a signature, assume the signature is valid, and want to know which public key signed it? A rather delightful property if you want to attack anonymity in some proposed “everybody just uses cryptographic signatures for everything” scheme.

New Blog Moderation Policy

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/06/new-blog-moderation-policy.html

There has been a lot of toxicity in the comments section of this blog. Recently, we’re having to delete more and more comments. Not just spam and off-topic comments, but also sniping and personal attacks. It’s gotten so bad that I need to do something.

My options are limited because I’m just one person, and this website is free, ad-free, and anonymous. I pay for a part-time moderator out of pocket; he isn’t able to constantly monitor comments. And I’m unwilling to require verified accounts.

So starting now, we will be pre-screening comments and letting through only those that 1) are on topic, 2) contribute to the discussion, and 3) don’t attack or insult anyone. The standard is not going to be “well, I guess this doesn’t technically quite break a rule,” but “is this actually contributing.”

Obviously, this is a subjective standard; sometimes good comments will accidentally get thrown out. And the delayed nature of the screening will result in less conversation and more disjointed comments. Those are costs, and they’re significant ones. But something has to be done, and I would like to try this before turning off all comments.

I am going to disable comments on the weekly squid posts. Topicality is too murky on an open thread, and these posts are especially hard to keep on top of.

Comments will be reviewed and published when possible, usually in the morning and evening. Sometimes it will take longer. Again, the moderator is part time, so please be patient.

I apologize to all those who have just kept commenting reasonably all along. But I’ve received three e-mails in the past couple of months about people who have given up on comments because of the toxicity.

So let’s see if this works. I’ve been able to maintain an anonymous comment section on this blog for almost twenty years. It’s kind of astounding that it’s worked as long as it has. Maybe its time is up.

Blue/Green Deployments to Amazon ECS using AWS CloudFormation and AWS CodeDeploy

Post Syndicated from Ajay Mehta original https://aws.amazon.com/blogs/devops/blue-green-deployments-to-amazon-ecs-using-aws-cloudformation-and-aws-codedeploy/

Introduction

Many customers use Amazon Elastic Container Service (ECS) for running their mission critical container-based applications on AWS. These customers are looking for safe deployment of application and infrastructure changes with minimal downtime, leveraging AWS CodeDeploy and AWS CloudFormation. AWS CloudFormation natively supports performing Blue/Green deployments on ECS using a CodeDeploy Blue/Green hook, but this feature comes with some additional considerations that are outlined here; one of them is the inability to use CloudFormation nested stacks, and another is the inability to update application and infrastructure changes in a single deployment. For these reasons, some customers may not be able to use the CloudFormation-based Blue/Green deployment capability for ECS. Additionally, some customers require more control over their Blue/Green deployment process and would therefore like CodeDeploy-based deployments to be performed outside of CloudFormation.

In this post, we will show you how to address these challenges by leveraging AWS CodeBuild and AWS CodePipeline to automate the configuration of CodeDeploy for performing Blue/Green deployments on ECS. We will also show how you can deploy both infrastructure and application changes through a single CodePipeline for your applications running on ECS.

The solution presented in this post is appropriate if you are using CloudFormation for your application infrastructure deployment. For AWS CDK applications, please refer to this post that walks through how you can enable Blue/Green deployments on ECS using CDK pipelines.

Reference Architecture

The diagram below shows a reference CICD pipeline for orchestrating a Blue/Green deployment for an ECS application. In this reference architecture, we assume that you are deploying both infrastructure and application changes through the same pipeline.

CICD Pipeline for performing Blue/Green deployment to an application running on ECS Fargate

Figure 1: CICD Pipeline for performing Blue/Green deployment to an application running on ECS Fargate Cluster

The pipeline consists of the following stages:

  1. Source: In the source stage, CodePipeline pulls the code from the source repository, such as AWS CodeCommit or GitHub, and stages the changes in S3.
  2. Build: In the build stage, you use CodeBuild to package CloudFormation templates, perform static analysis for the application code as well as the application infrastructure templates, run unit tests, build the application code, and generate and publish the application container image to ECR. These steps can be performed using a series of CodeBuild steps as described in the reference pipeline above.
  3. Deploy Infrastructure: In the deploy stage, you leverage CodePipeline’s CloudFormation deploy action to deploy or update the application infrastructure. In this stage, the entire application infrastructure is set up using CloudFormation nested stacks. This includes the components required to perform Blue/Green deployments on ECS using CodeDeploy, such as the ECS Cluster, ECS Service, Task definition, Application Load Balancer (ALB) listeners, target groups, CodeDeploy application, deployment group, and others.
  4. Deploy Application: In the deploy application stage, you use the CodePipeline ECS-to-CodeDeploy action to deploy your application changes using CodeDeploy’s blue/green deployment capability. By leveraging CodeDeploy, you can automate the blue/green deployment workflow for your applications running on ECS, including testing of your application after deployment and automated rollbacks in case of failed deployments. CodeDeploy also offers different ways to switch traffic for your application during a blue/green deployment by supporting Linear, Canary, and All-at-once traffic shifting options. More information on CodeDeploy’s Blue/Green deployment workflow for ECS can be found here

Considerations

Some considerations that you may need to account for when implementing the above reference pipeline

1. Creating the CodeDeploy deployment group using CloudFormation
For performing Blue/Green deployments using CodeDeploy on ECS, CloudFormation currently does not support creating the CodeDeploy components directly as these components are created and managed by CloudFormation through the AWS::CodeDeploy::BlueGreen hook. To work around this, you can leverage a CloudFormation custom resource implemented through an AWS Lambda function, to create the CodeDeploy Deployment group with the required configuration. A reference implementation of a CloudFormation custom resource lambda can be found in our solution’s reference implementation here.

2. Generating the required code deploy artifacts (appspec.yml and taskdef.json)
For leveraging the CodeDeployToECS action in CodePipeline, there are two input files (appspec.yml and taskdef.json) that are needed. These files/artifacts are used by CodePipeline to create a CodeDeploy deployment that performs Blue/Green deployment on your ECS cluster. The AppSpec file specifies an Amazon ECS task definition for the deployment, a container name and port mapping used to route traffic, and the Lambda functions that run after deployment lifecycle hooks. The container name must be a container in your Amazon ECS task definition. For more information on these, see Working with application revisions for CodeDeploy. The taskdef.json is used by CodePipeline to dynamically generate a new revision of the task definition with the updated application container image in ECR. This is an optional capability supported by the CodeDeployToECS action where it can automatically replace a place holder value (for example IMAGE1_NAME) for ImageUri in the taskdef.json with the Uri of the updated container Image. In the reference solution we do not use this capability as our taskdef.json contains the latest ImageUri that we plan to deploy. To create this taskdef.json, you can leverage CodeBuild to dynamically build the taskdef.json from the latest task definition ARN. Below are sample CodeBuild buildspec commands that creates the taskdef.json from ECS task definition

build:
    commands:
        # Create appspec.yml for CodeDeploy deployment
        - python iac/code-deploy/scripts/update-appspec.py --taskArn ${TASKDEF_ARN} --hooksLambdaArn ${HOOKS_LAMBDA_ARN} --inputAppSpecFile 'iac/code-deploy/appspec.yml' --outputAppSpecFile '/tmp/appspec.yml'
        # Create taskdefinition for CodeDeploy deployment
        - aws ecs describe-task-definition --task-definition ${TASKDEF_ARN} --region ${AWS_REGION} --query taskDefinition >> taskdef.json
    artifacts:
        files:
            - /tmp/appspec.yml
            - /tmp/taskdef.json
        discard-paths: yes

To generate the appspec.yml, you can leverage a python or shell script and a placeholder appspec.yml in your source repository to dynamically generate the updated appspec.yml file. For example, the below code snippet updates the placeholder values in an appspec.yml to generate an updated appspec.yml that is used in the deploy stage. In this example, we set the values of AfterAllowTestTraffic hook, the Container name, Container port values from task definition and Hooks Lambda ARN that is passed as input to the script.


  contents = yaml.safe_load(file)
  print(contents)
  response = ecs.describe_task_definition(taskDefinition=taskArn)
  contents['Hooks'][0]['AfterAllowTestTraffic'] = hooksLambdaArn
  contents['Resources'][0]['TargetService']['Properties']['LoadBalancerInfo']['ContainerName'] = response['taskDefinition']['containerDefinitions'][0]['name']
  contents['Resources'][0]['TargetService']['Properties']['LoadBalancerInfo']['ContainerPort'] = response['taskDefinition']['containerDefinitions'][0]['portMappings'][0]['containerPort']
  contents['Resources'][0]['TargetService']['Properties']['TaskDefinition'] = taskArn

  print('Updated appspec.yaml contents')
  yaml.dump(contents, outputFile)

In the above scenario, the existing task definition is used to build the appspec.yml. You can also specify one of more CodeDeploy lambda based hooks in the appspec.yml to perform variety of automated tests as part of your deployment.

3. Updates to the ECS task definition
To perform Blue/Green deployments on your ECS cluster using CodeDeploy, the deployment controller on the ECS Service needs to be set to CodeDeploy. With this configuration, any time there is an update to the task definition on the ECS service (such as when building new application image), the update results in a failure. This essentially causes CloudFormation updates to the application infrastructure to fail when new application changes are deployed. To avoid this, you can implement a CloudFormation based custom resource that obtains the previous version of task definition. This prevents CloudFormation from updating the ECS Service with new task definition when the application container image is updated and ultimately from failing the stack update. Updates to ECS Services for new task revisions are performed using the CodeDeploy deployment as outlined in #2 above. Using this mechanism, you can update the application infrastructure along with changes to the application code using a single pipeline while also leveraging CodeDeploy Blue/Green deployment.

4. Passing configuration between different stages of the pipeline
To create an automated pipeline that builds your infrastructure and performs a blue/green deployment for your application, you will need the ability to pass configuration between different stages of your pipeline. For example, when you want to create the taskdef.json and appspec.yml as mentioned in step #2, you need the ARN of the existing task definition and ARN of the CodeDeploy hook Lambda. These components are created in different stages within your pipeline. To facilitate this, you can leverage CodePipeline’s variables and namespaces. For example, in the CodePipeline stage below, we set the value of TASKDEF_ARN and HOOKS_LAMBDA_ARN environment variables by fetching those values from a different stage in the same pipeline where we create those components. An alternate option is to use AWS System Manager Parameter Store to store and retrieve that information. Additional information about CodePipeline’s variables and how to use them can be found in our documentation here.


- Name: BuildCodeDeployArtifacts
  Actions:
	- Name: BuildCodeDeployArtifacts
	  ActionTypeId:
		Category: Build
		Owner: AWS
		Provider: CodeBuild
		Version: "1"
	  Configuration:
		ProjectName: !Sub "${pApplicationName}-CodeDeployConfigBuild"
		EnvironmentVariables: '[{"name": "TASKDEF_ARN", "value": "#{DeployInfraVariables.oTaskDefinitionArn}", "type": "PLAINTEXT"},{"name": "HOOKS_LAMBDA_ARN", "value": "#{DeployInfraVariables.oAfterInstallHookLambdaArn}", "type": "PLAINTEXT"}]'
	  InputArtifacts:
		- Name: Source
	  OutputArtifacts:
		- Name: CodeDeployConfig
	  RunOrder: 1

Reference Solution:

As part of this post we have provided a reference solution that performs a Blue/Green deployment for a sample Java based application running on ECS Fargate using CodePipeline and CodeDeploy. The reference implementation provides CloudFormation templates to create the necessary CodeDeploy components, including custom resources for Blue/Green deployment on Amazon ECS, as well as the application infrastructure using nested stacks. The solution also provides a reference CodePipeline implementation that fully orchestrates the application build, test and blue/green deployment. In the solution we also demonstrate how you can orchestrate Blue/Green deployment using Linear, Canary, and All-at-once traffic shifting patterns. You can download the reference implementation from here. You can further customize this solution by building your own CodeDeploy lifecycle hooks and run additional configuration and validation tasks as per you application needs. We also recommend that you look at our Deployment Pipeline Reference Architecture (DPRA) and enhance your delivery pipelines by including additional stages and actions that meet your needs.

Conclusion:

In this post we walked through how you can automate Blue/Green deployment of your ECS based application leveraging AWS CodePipeline, AWS CodeDeploy and AWS CloudFormation nested stacks. We reviewed what you need to consider for automating Blue/Green deployment for your application running on your ECS cluster using CodePipeline and CodeDeploy and how you can address those challenges with some scripting and CloudFormation Lambda based custom resource. We hope that this helps you in configuring Blue/Green deployments on your ECS based application using CodePipeline and CodeDeploy.

Ajay Mehta is a Principal Cloud Infrastructure Architect for AWS Professional Services. He works with Enterprise customers accelerate their cloud adoption through building Landing Zones and transforming IT organizations to adopt cloud operating practices and agile operations. When not working he enjoys spending time with family, traveling, and exploring new places.

Santosh Kale is a Senior DevOps Architect at AWS Professional Services, passionate about Kubernetes and GenAI-AI/ML. As a DevOps and MLOps SME, he is an active member of AWS Containers, MLOps Area-of-Depth team and helps Enterprise High-Tech customers on their transformative journeys through DevOps/MLOps adoption and Containers modernization technologies. Beyond Cloud, he is a Nature Lover and enjoys quality time visiting scenic places around the world.

The Hacking of Culture and the Creation of Socio-Technical Debt

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/06/the-hacking-of-culture-and-the-creation-of-socio-technical-debt.html

Culture is increasingly mediated through algorithms. These algorithms have splintered the organization of culture, a result of states and tech companies vying for influence over mass audiences. One byproduct of this splintering is a shift from imperfect but broad cultural narratives to a proliferation of niche groups, who are defined by ideology or aesthetics instead of nationality or geography. This change reflects a material shift in the relationship between collective identity and power, and illustrates how states no longer have exclusive domain over either. Today, both power and culture are increasingly corporate.

Blending Stewart Brand and Jean-Jacques Rousseau, McKenzie Wark writes in A Hacker Manifesto that “information wants to be free but is everywhere in chains.”1 Sounding simultaneously harmless and revolutionary, Wark’s assertion as part of her analysis of the role of what she terms “the hacker class” in creating new world orders points to one of the main ideas that became foundational to the reorganization of power in the era of the internet: that “information wants to be free.” This credo, itself a co-option of Brand’s influential original assertion in a conversation with Apple cofounder Steve Wozniak at the 1984 Hackers Conference and later in his 1987 book The Media Lab: Inventing the Future at MIT, became a central ethos for early internet inventors, activists,2 and entrepreneurs. Ultimately, this notion was foundational in the construction of the era we find ourselves in today: an era in which internet companies dominate public and private life. These companies used the supposed desire of information to be free as a pretext for building platforms that allowed people to connect and share content. Over time, this development helped facilitate the definitive power transfer of our time, from states to corporations.

This power transfer was enabled in part by personal data and its potential power to influence people’s behavior—a critical goal in both politics and business. The pioneers of the digital advertising industry claimed that the more data they had about people, the more they could influence their behavior. In this way, they used data as a proxy for influence, and built the business case for mass digital surveillance. The big idea was that data can accurately model, predict, and influence the behavior of everyone—from consumers to voters to criminals. In reality, the relationship between data and influence is fuzzier, since influence is hard to measure or quantify. But the idea of data as a proxy for influence is appealing precisely because data is quantifiable, whereas influence is vague. The business model of Google Ads, Facebook, Experian, and similar companies works because data is cheap to gather, and the effectiveness of the resulting influence is difficult to measure. The credo was “Build the platform, harvest the data…then profit.” By 2006, a major policy paper could ask, “Is Data the New Oil?”3

The digital platforms that have succeeded most in attracting and sustaining mass attention—Facebook, TikTok, Instagram—have become cultural. The design of these platforms dictates the circulation of customs, symbols, stories, values, and norms that bind people together in protocols of shared identity. Culture, as articulated through human systems such as art and media, is a kind of social infrastructure. Put differently, culture is the operating system of society.

Like any well-designed operating system, culture is invisible to most people most of the time. Hidden in plain sight, we make use of it constantly without realizing it. As an operating system, culture forms the base infrastructure layer of societal interaction, facilitating communication, cooperation, and interrelations. Always evolving, culture is elastic: we build on it, remix it, and even break it.

Culture can also be hacked—subverted for specific advantage.4 If culture is like an operating system, then to hack it is to exploit the design of that system to gain unauthorized control and manipulate it towards a specific end. This can be for good or for bad. The morality of the hack depends on the intent and actions of the hacker.

When businesses hack culture to gather data, they are not necessarily destroying or burning down social fabrics and cultural infrastructure. Rather, they reroute the way information and value circulate, for the benefit of their shareholders. This isn’t new. There have been culture hacks before. For example, by lending it covert support, the CIA hacked the abstract expressionism movement to promote the idea that capitalism was friendly to high culture.5 Advertising appropriated the folk-cultural images of Santa Claus and the American cowboy to sell Coca-Cola and Marlboro cigarettes, respectively. In Mexico, after the revolution of 1910, the ruling party hacked muralist works, aiming to construct a unifying national narrative.

Culture hacks under digital capitalism are different. Whereas traditional propaganda goes in one direction—from government to population, or from corporation to customers—the internet-surveillance business works in two directions: extracting data while pushing engaging content. The extracted data is used to determine what content a user would find most engaging, and that engagement is used to extract more data, and so on. The goal is to keep as many users as possible on platforms for as long as possible, in order to sell access to those users to advertisers. Another difference between traditional propaganda and digital platforms is that the former aims to craft messages with broad appeal, while the latter hyper-personalizes content for individual users.

The rise of Chinese-owned TikTok has triggered heated debate in the US about the potential for a foreign-owned platform to influence users by manipulating what they see. Never mind that US corporations have used similar tactics for years. While the political commitments of platform owners are indeed consequential—Chinese-owned companies are in service to the Chinese Communist Party, while US-owned companies are in service to business goals—the far more pressing issue is that both have virtually unchecked surveillance power. They are both reshaping societies by hacking culture to extract data and serve content. Funny memes, shocking news, and aspirational images all function similarly: they provide companies with unprecedented access to societies’ collective dreams and fears.6 By determining who sees what when and where, platform owners influence how societies articulate their understanding of themselves.

Tech companies want us to believe that algorithmically determined content is effectively neutral: that it merely reflects the user’s behavior and tastes back at them. In 2021, Instagram head Adam Mosseri wrote a post on the company’s blog entitled “Shedding More Light on How Instagram Works.” A similar window into TikTok’s functioning was provided by journalist Ben Smith in his article “How TikTok Reads Your Mind.”7 Both pieces boil down to roughly the same idea: “We use complicated math to give you more of what your behavior shows us you really like.”

This has two consequences. First, companies that control what users see in a nontransparent way influence how we perceive the world. They can even shape our personal relationships. Second, by optimizing algorithms for individual attention, a sense of culture as common ground is lost. Rather than binding people through shared narratives, digital platforms fracture common cultural norms into self-reinforcing filter bubbles.8

This fragmentation of shared cultural identity reflects how the data surveillance business is rewriting both the established order of global power, and social contracts between national governments and their citizens. Before the internet, in the era of the modern state, imperfect but broad narratives shaped distinct cultural identities; “Mexican culture” was different from “French culture,” and so on. These narratives were designed to carve away an “us” from “them,” in a way that served government aims. Culture has long been understood to operate within the envelope of nationality, as exemplified by the organization of museum collections according to the nationality of artists, or by the Venice Biennale—the Olympics of the art world, with its national pavilions format.

National culture, however, is about more than museum collections or promoting tourism. It broadly legitimizes state power by emotionally binding citizens to a self-understood identity. This identity helps ensure a continuing supply of military recruits to fight for the preservation of the state. Sociologist James Davison Hunter, who popularized the phrase “culture war,” stresses that culture is used to justify violence to defend these identities.9 We saw an example of this on January 6, 2021, with the storming of the US Capitol. Many of those involved were motivated by a desire to defend a certain idea of cultural identity they believed was under threat.

Military priorities were also entangled with the origins of the tech industry. The US Department of Defense funded ARPANET, the first version of the internet. But the internet wouldn’t have become what it is today without the influence of both West Coast counterculture and small-l libertarianism, which saw the early internet as primarily a space to connect and play. One of the first digital game designers was Bernie De Koven, founder of the Games Preserve Foundation. A noted game theorist, he was inspired by Stewart Brand’s interest in “play-ins” to start a center dedicated to play. Brand had envisioned play-ins as an alternative form of protest against the Vietnam War; they would be their own “soft war” of subversion against the military.10 But the rise of digital surveillance as the business model of nascent tech corporations would hack this anti-establishment spirit, turning instruments of social cohesion and connection into instruments of control.

It’s this counterculture side of tech’s lineage, which advocated for the social value of play, that attuned the tech industry to the utility of culture. We see the commingling of play and military control in Brand’s Whole Earth Catalog, which was a huge influence on early tech culture. Described as “a kind of Bible for counterculture technology,” the Whole Earth Catalog was popular with the first generation of internet engineers, and established crucial “assumptions about the ideal relationships between information, technology, and community.”11 Brand’s 1972 Rolling Stone article “Spacewar: Fantastic Life and Symbolic Death Among the Computer” further emphasized how rudimentary video games were central to the engineering community. These games were wildly popular at leading engineering research centers: Stanford, MIT, ARPA, Xerox, and others. This passion for gaming as an expression of technical skills and a way for hacker communities to bond led to the development of MUD (Multi-User Dungeon) programs, which enabled multiple people to communicate and collaborate online simultaneously.

The first MUD was developed in 1978 by engineers who wanted to play fantasy games online. It applied the early-internet ethos of decentralism and personalization to video games, making it a precursor to massive multiplayer online role-playing games and modern chat rooms and Facebook groups. Today, these video games and game-like simulations—now a commercial industry worth around $200 billion12—serve as important recruitment and training tools for the military.13 The history of the tech industry and culture is full of this tension between the internet as an engineering plaything and as a surveillance commodity.

Historically, infrastructure businesses—like railroad companies in the nineteenth-century US—have always wielded considerable power. Internet companies that are also infrastructure businesses combine commercial interests with influence over national and individual security. As we transitioned from railroad tycoons connecting physical space to cloud computing companies connecting digital space, the pace of technological development put governments at a disadvantage. The result is that corporations now lead the development of new tech (a reversal from the ARPANET days), and governments follow, struggling to modernize public services in line with the new tech. Companies like Microsoft are functionally providing national cybersecurity. Starlink, Elon Musk’s satellite internet service, is a consumer product that facilitates military communications for the war in Ukraine. Traditionally, this kind of service had been restricted to selected users and was the purview of states.14 Increasingly, it is clear that a handful of transnational companies are using their technological advantages to consolidate economic and political power to a degree previously afforded to only great-power nations.

Worse, since these companies operate across multiple countries and regions, there is no regulatory body with the jurisdiction to effectively constrain them. This transition of authority from states to corporations and the nature of surveillance as the business model of the internet rewrites social contracts between national governments and their citizens. But it also also blurs the lines among citizen, consumer, and worker. An example of this are Google’s Recaptchas, visual image puzzles used in cybersecurity to “prove” that the user is a human and not a bot. While these puzzles are used by companies and governments to add a layer of security to their sites, their value is in how they record a user’s input in solving the puzzles to train Google’s computer vision AI systems. Similarly, Microsoft provides significant cybersecurity services to governments while it also trains its AI models on citizens’ conversations with Bing.15 Under this dyanmic, when citizens use digital tools and services provided by tech companies, often to access government webpages and resources, they become de facto free labor for the tech companies providing them. The value generated by this citizen-user-laborer stays with the company, as it is used to develop and refine their products. In this new blurred reality, the relationships among corporations, governments, power, and identity are shifting. Our social and cultural infrastructure suffers as a result, creating a new kind of technical debt of social and cultural infrustructure.

In the field of software development, technical debt refers to the future cost of ignoring a near-term engineering problem.16 Technical debt grows as engineers implement short-term patches or workarounds, choosing to push the more expensive and involved re-engineering fixes for later. This debt accrues over time, to be paid back in the long term. The result of a decision to solve an immediate problem at the expense of the long-term one effectively mortgages the future in favor of an easier present. In terms of cultural and social infrastructure, we use the same phrase to refer to the long-term costs that result from avoiding or not fully addressing social needs in the present. More than a mere mistake, socio-technical debt stems from willfully not addressing a social problem today and leaving a much larger problem to be addressed in the future.

For example, this kind of technical debt was created by the cratering of the news industry, which relied on social media to drive traffic—and revenue—to news websites. When social media companies adjusted their algorithms to deprioritize news, traffic to news sites plummeted, causing an existential crisis for many publications.17 Now, traditional news stories make up only 3 percent of social media content. At the same time, 66 percent of people ages eighteen to twenty-four say they get their “news” from TikTok, Facebook, and Twitter.18 To be clear, Facebook did not accrue technical debt when it swallowed the news industry. We as a society are dealing with technical debt in the sense that we are being forced to pay the social cost of allowing them to do that.

One result of this shift in information consumption as a result of changes to the cultural infrastructure of social media is the rise in polarization and radicalism. So by neglecting to adequately regulate tech companies and support news outlets in the near term, our governments have paved the way for social instability in the long term. We as a society also have to find and fund new systems to act as a watchdog over both corporate and governmental power.

Another example of socio-technical debt is the slow erosion of main streets and malls by e-commerce.19 These places used to be important sites for physical gathering, which helped the shops and restaurants concentrated there stay in business. But e-commerce and direct-to-consumer trends have undermined the economic viability of main streets and malls, and have made it much harder for small businesses to survive. The long-term consequence of this to society is the hollowing out of town centers and the loss of spaces for physical gathering—which we will all have to pay for eventually.

The faltering finances of museums will also create long-term consequences for society as a whole, especially in the US, where Museums mostly depend on private donors to cover operational costs. But a younger generation of philanthropists is shifting its giving priorities away from the arts, leading to a funding crisis at some institutions.20

One final example: libraries. NYU Sociologist Eric Klinenberg called libraries “the textbook example of social infrastructure in action.”21 But today they are stretched to the breaking point, like museums, main streets, and news media. In New York City, Mayor Eric Adams has proposed a series of severe budget cuts to the city’s library system over the past year, despite having seen a spike in usage recently. The steepest cuts were eventually retracted, but most libraries in the city have still had to cancel social programs and cut the number of days they’re open.22 As more and more spaces for meeting in real life close, we increasingly turn to digital platforms for connection to replace them. But these virtual spaces are optimized for shareholder returns, not public good.

Just seven companies—Alphabet (the parent company of Google), Amazon, Apple, Meta, Microsoft, Nvidia and Tesla—drove 60 percent of the gains of the S&P stock market index in 2023.23 Four—Alibaba, Amazon, Google, and Microsoft—deliver the majority of cloud services.24 These companies have captured the delivery of digital and physical goods and services. Everything involved with social media, cloud computing, groceries, and medicine is trapped in their flywheels, because the constellation of systems that previously put the brakes on corporate power, such as monopoly laws, labor unions, and news media, has been eroded. Product dependence and regulatory capture have further undermined the capacity of states to respond to the rise in corporate hard and soft power. Lock-in and other anticompetitive corporate behavior have prevented market mechanisms from working properly. As democracy falls into deeper crisis with each passing year, policy and culture are increasingly bent towards serving corporate interest. The illusion that business, government, and culture are siloed sustains this status quo.

Our digitized global economy has made us all participants in the international data trade, however reluctantly. Though we are aware of the privacy invasions and social costs of digital platforms, we nevertheless participate in these systems because we feel as though we have no alternative—which itself is partly the result of tech monopolies and the lack of competition.

Now, the ascendence of AI is thrusting big data into a new phase and new conflicts with social contracts. The development of bigger, more powerful AI models means more demand for data. Again, massive wholesale extractions of culture are at the heart of these efforts.25 As AI researchers and artists Kate Crawford and Vladan Joler explain in the catalog to their exhibition Calculating Empires, AI developers require “the entire history of human knowledge and culture … The current lawsuits over generative systems like GPT and Stable Diffusion highlight how completely dependent AI systems are on extracting, enclosing, and commodifying the entire history of cognitive and creative labor.”26

Permitting internet companies to hack the systems in which culture is produced and circulates is a short-term trade-off that has proven to have devastating long-term consequences. When governments give tech companies unregulated access to our social and cultural infrastructure, the social contract becomes biased towards their profit. When we get immediate catharsis through sharing memes or engaging in internet flamewars, real protest is muzzled. We are increasing our collective socio-technical debt by ceding our social and cultural infrastructure to tech monopolies.

Cultural expression is fundamental to what makes us human. It’s an impulse, innate to us as a species, and this impulse will continue to be a gold mine to tech companies. There is evidence that AI models trained on synthetic data—data produced by other AI models rather than humans—can corrupt these models, causing them to return false or nonsensical answers to queries.27 So as AI-produced data floods the internet, data that is guaranteed to have been derived from humans becomes more valuable. In this context, our human nature, compelling us to make and express culture, is the dream of digital capitalism. We become a perpetual motion machine churning out free data. Beholden to shareholders, these corporations see it as their fiduciary duty—a moral imperative even—to extract value from this cultural life.

We are in a strange transition. The previous global order, in which states wielded ultimate authority, hasn’t quite died. At the same time, large corporations have stepped in to deliver some of the services abandoned by states, but at the price of privacy and civic well-being. Increasingly, corporations provide consistent, if not pleasant, economic and social organization. Something similar occurred during the Gilded Age in the US (1870s–1890s). But back then, the influence of robber barons was largely constrained to the geographies in which they operated, and their services (like the railroad) were not previously provided by states. In our current transitionary period, public life worldwide is being reimagined in accordance with corporate values. Amidst a tug-of-war between the old state-centric world and the emerging capital-centric world, there is a growing radicalism fueled partly by frustration over social and personal needs going unmet under a transnational order that is maximized for profit rather than public good.

Culture is increasingly divorced from national identity in our globalized, fragmented world. On the positive side, this decoupling can make culture more inclusive of marginalized people. Other groups, however, may perceive this new status quo as a threat, especially those facing a loss of privilege. The rise of white Christian nationalism shows that the right still regards national identity and culture as crucial—as potent tools in the struggle to build political power, often through anti-democratic means. This phenomenon shows that the separation of cultural identity from national identity doesn’t negate the latter. Instead, it creates new political realities and new orders of power.

Nations issuing passports still behave as though they are the definitive arbiters of identity. But culture today—particularly the multiverse of internet cultures—exposes how this is increasingly untrue. With government discredited as an ultimate authority, and identity less and less connected to nationality, we can find a measure of hope for navigating the current transition in the fact that culture is never static. New forms of resistance are always emerging. But we must ask ourselves: Have the tech industry’s overwhelming surveillance powers rendered subversion impossible? Or does its scramble to gather all the world’s data offer new possibilities to hack the system?


1. McKenzie Wark, A Hacker Manifesto (Harvard University Press, 2004), thesis 126.

2. Jon Katz, “Birth of a Digital Nation,” Wired, April 1, 1997.

3. Marcin Szczepanski, “Is Data the New Oil? Competition Issues in the Digital Economy,” European Parliamentary Research Service, January 2020.

4. Bruce Schneier, A Hacker’s Mind: How the Powerful Bend Society’s Rules, and How to Bend Them Back (W. W. Norton & Sons, 2023).

5. Lucie Levine, “Was Modern Art Really a CIA Psy-Op?” JStor Daily, April 1, 2020.

6. Bruce Schneier, Data and Goliath: The Hidden Battles to Collect Your Data and Control Your World (W. W. Norton & Sons, 2015).

7. Adam Mosseri, “Shedding More Light on How Instagram Works,” Instagram Blog, June 8, 2021; Ben Smith, “How TikTok Reads Your Mind,” New York Times, December 5, 2021.

8. Giacomo Figà Talamanca and Selene Arfini, “Through the Newsfeed Glass: Rethinking Filter Bubbles and Echo Chambers,” Philosophy & Technology 35, no. 1 (2022).

9. Zack Stanton, “How the ‘Culture War’ Could Break Democracy,” Politico, May 5, 2021.

10. Jason Johnson, “Inside the Failed, Utopian New Games Movement,” Kill Screen, October 25, 2013.

11. Fred Turner, “Taking the Whole Earth Digital,” chap. 4 in From Counter Culture to Cyberculture: Stewart Brand, The Whole Earth Network, and the Rise of Digital Utopianism (University of Chicago Press, 2006).

12. Kaare Ericksen, “The State of the Video Games Industry: A Special Report,” Variety, February 1, 2024.

13. Rosa Schwartzburg, “The US Military Is Embedded in the Gaming World. It’s Target: Teen Recruits,” The Guardian, February 14, 2024; Scott Kuhn, “Soldiers Maintain Readiness Playing Video Games,” US Army, April 29, 2020; Katie Lange, “Military Esports: How Gaming Is Changing Recruitment & Moral,” US Department of Defense, December 13, 2022.

14. Shaun Waterman, “Growing Commercial SATCOM Raises Trust Issues for Pentagon,” Air & Space Forces Magazine, April 3, 2024.

15. Geoffrey A Fowler, “Your Instagrams Are Training AI. There’s Little You Can Do About It,” Washington Post, September 27, 2023.

16. Zengyang Li, Paris Avgeriou, and Peng Liang, “A Systematic Mapping Study on Technical Debt and Its Management,” Journal of Systems and Software, December 2014.

17. David Streitfeld, “How the Media Industry Keeps Losing the Future,” New York Times, February 28, 2024.

18. “The End of the Social Network,” The Economist, February 1, 2024; Ollie Davies, “What Happens If Teens Get Their News From TikTok?” The Guardian, February 22, 2023.

19. Eric Jaffe, “Quantifying the Death of the Classic American Main Street,” Medium, March 16, 2018.

20. Julia Halprin, “The Hangover from the Museum Party: Institutions in the US Are Facing a Funding Crisis,” Art Newspaper, January 19, 2024.

21. Quoted in Pete Buttigieg, “The Key to Happiness Might Be as Simple as a Library or Park,” New York Times, September 14, 2018.

22. Jeffery C. Mays and Dana Rubinstein, “Mayor Adams Walks Back Budget Cuts Many Saw as Unnecessary,” New York Times, April 24, 2024.

23. Karl Russell and Joe Rennison, “These Seven Tech Stocks Are Driving the Market,” New York Times, January 22, 2024.

24. Ian Bremmer, “How Big Tech Will Reshape the Global Order,” Foreign Affairs, October 19, 2021.

25. Nathan Sanders and Bruce Schneier, “How the ‘Frontier’ Became the Slogan for Uncontrolled AI,” Jacobin, February 27, 2024.

26. Kate Crawford and Vladan Joler, Calculating Empires: A Genealogy of Technology and Power, 1500–2025 (Fondazione Prada, 2023), 9. Exhibition catalog.

27. Rahul Rao, “AI Generated Data Can Poison Future AI Models,” Scientific American, July 28, 2023.

This essay was written with Kim Córdova, and was originally published in e-flux.
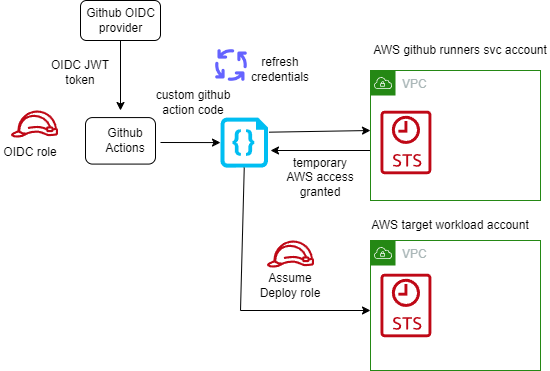
Rethinking Democracy for the Age of AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/06/rethinking-democracy-for-the-age-of-ai.html

There is a lot written about technology’s threats to democracy. Polarization. Artificial intelligence. The concentration of wealth and power. I have a more general story: The political and economic systems of governance that were created in the mid-18th century are poorly suited for the 21st century. They don’t align incentives well. And they are being hacked too effectively.

At the same time, the cost of these hacked systems has never been greater, across all human history. We have become too powerful as a species. And our systems cannot keep up with fast-changing disruptive technologies.

We need to create new systems of governance that align incentives and are resilient against hacking … at every scale. From the individual all the way up to the whole of society.

For this, I need you to drop your 20th century either/or thinking. This is not about capitalism versus communism. It’s not about democracy versus autocracy. It’s not even about humans versus AI. It’s something new, something we don’t have a name for yet. And it’s “blue sky” thinking, not even remotely considering what’s feasible today.

Throughout this talk, I want you to think of both democracy and capitalism as information systems. Socio-technical information systems. Protocols for making group decisions. Ones where different players have different incentives. These systems are vulnerable to hacking and need to be secured against those hacks.

We security technologists have a lot of expertise in both secure system design and hacking. That’s why we have something to add to this discussion.

And finally, this is a work in progress. I’m trying to create a framework for viewing governance. So think of this more as a foundation for discussion, rather than a road map to a solution. And I think by writing, and what you’re going to hear is the current draft of my writing—and my thinking. So everything is subject to change without notice.

OK, so let’s go.

We all know about misinformation and how it affects democracy. And how propagandists have used it to advance their agendas. This is an ancient problem, amplified by information technologies. Social media platforms that prioritize engagement. “Filter bubble” segmentation. And technologies for honing persuasive messages.

The problem ultimately stems from the way democracies use information to make policy decisions. Democracy is an information system that leverages collective intelligence to solve political problems. And then to collect feedback as to how well those solutions are working. This is different from autocracies that don’t leverage collective intelligence for political decision making. Or have reliable mechanisms for collecting feedback from their populations.

Those systems of democracy work well, but have no guardrails when fringe ideas become weaponized. That’s what misinformation targets. The historical solution for this was supposed to be representation. This is currently failing in the US, partly because of gerrymandering, safe seats, only two parties, money in politics and our primary system. But the problem is more general.

James Madison wrote about this in 1787, where he made two points. One, that representatives serve to filter popular opinions, limiting extremism. And two, that geographical dispersal makes it hard for those with extreme views to participate. It’s hard to organize. To be fair, these limitations are both good and bad. In any case, current technology—social media—breaks them both.

So this is a question: What does representation look like in a world without either filtering or geographical dispersal? Or, how do we avoid polluting 21st century democracy with prejudice, misinformation and bias. Things that impair both the problem solving and feedback mechanisms.

That’s the real issue. It’s not about misinformation, it’s about the incentive structure that makes misinformation a viable strategy.

This is problem No. 1: Our systems have misaligned incentives. What’s best for the small group often doesn’t match what’s best for the whole. And this is true across all sorts of individuals and group sizes.

Now, historically, we have used misalignment to our advantage. Our current systems of governance leverage conflict to make decisions. The basic idea is that coordination is inefficient and expensive. Individual self-interest leads to local optimizations, which results in optimal group decisions.

But this is also inefficient and expensive. The U.S. spent $14.5 billion on the 2020 presidential, senate and congressional elections. I don’t even know how to calculate the cost in attention. That sounds like a lot of money, but step back and think about how the system works. The economic value of winning those elections are so great because that’s how you impose your own incentive structure on the whole.

More generally, the cost of our market economy is enormous. For example, $780 billion is spent world-wide annually on advertising. Many more billions are wasted on ventures that fail. And that’s just a fraction of the total resources lost in a competitive market environment. And there are other collateral damages, which are spread non-uniformly across people.

We have accepted these costs of capitalism—and democracy—because the inefficiency of central planning was considered to be worse. That might not be true anymore. The costs of conflict have increased. And the costs of coordination have decreased. Corporations demonstrate that large centrally planned economic units can compete in today’s society. Think of Walmart or Amazon. If you compare GDP to market cap, Apple would be the eighth largest country on the planet. Microsoft would be the tenth.

Another effect of these conflict-based systems is that they foster a scarcity mindset. And we have taken this to an extreme. We now think in terms of zero-sum politics. My party wins, your party loses. And winning next time can be more important than governing this time. We think in terms of zero-sum economics. My product’s success depends on my competitors’ failures. We think zero-sum internationally. Arms races and trade wars.

Finally, conflict as a problem-solving tool might not give us good enough answers anymore. The underlying assumption is that if everyone pursues their own self interest, the result will approach everyone’s best interest. That only works for simple problems and requires systemic oppression. We have lots of problems—complex, wicked, global problems—that don’t work that way. We have interacting groups of problems that don’t work that way. We have problems that require more efficient ways of finding optimal solutions.

Note that there are multiple effects of these conflict-based systems. We have bad actors deliberately breaking the rules. And we have selfish actors taking advantage of insufficient rules.

The latter is problem No. 2: What I refer to as “hacking” in my latest book: “A Hacker’s Mind.” Democracy is a socio-technical system. And all socio-technical systems can be hacked. By this I mean that the rules are either incomplete or inconsistent or outdated—they have loopholes. And these can be used to subvert the rules. This is Peter Thiel subverting the Roth IRA to avoid paying taxes on $5 billion in income. This is gerrymandering, the filibuster, and must-pass legislation. Or tax loopholes, financial loopholes, regulatory loopholes.

In today’s society, the rich and powerful are just too good at hacking. And it is becoming increasingly impossible to patch our hacked systems. Because the rich use their power to ensure that the vulnerabilities don’t get patched.

This is bad for society, but it’s basically the optimal strategy in our competitive governance systems. Their zero-sum nature makes hacking an effective, if parasitic, strategy. Hacking isn’t a new problem, but today hacking scales better—and is overwhelming the security systems in place to keep hacking in check. Think about gun regulations, climate change, opioids. And complex systems make this worse. These are all non-linear, tightly coupled, unrepeatable, path-dependent, adaptive, co-evolving systems.

Now, add into this mix the risks that arise from new and dangerous technologies such as the internet or AI or synthetic biology. Or molecular nanotechnology, or nuclear weapons. Here, misaligned incentives and hacking can have catastrophic consequences for society.

This is problem No. 3: Our systems of governance are not suited to our power level. They tend to be rights based, not permissions based. They’re designed to be reactive, because traditionally there was only so much damage a single person could do.

We do have systems for regulating dangerous technologies. Consider automobiles. They are regulated in many ways: drivers licenses + traffic laws + automobile regulations + road design. Compare this to aircrafts. Much more onerous licensing requirements, rules about flights, regulations on aircraft design and testing and a government agency overseeing it all day-to-day. Or pharmaceuticals, which have very complex rules surrounding everything around researching, developing, producing and dispensing. We have all these regulations because this stuff can kill you.

The general term for this kind of thing is the “precautionary principle.” When random new things can be deadly, we prohibit them unless they are specifically allowed.

So what happens when a significant percentage of our jobs are as potentially damaging as a pilot’s? Or even more damaging? When one person can affect everyone through synthetic biology. Or where a corporate decision can directly affect climate. Or something in AI or robotics. Things like the precautionary principle are no longer sufficient. Because breaking the rules can have global effects.

And AI will supercharge hacking. We have created a series of non-interoperable systems that actually interact and AI will be able to figure out how to take advantage of more of those interactions: finding new tax loopholes or finding new ways to evade financial regulations. Creating “micro-legislation” that surreptitiously benefits a particular person or group. And catastrophic risk means this is no longer tenable.

So these are our core problems: misaligned incentives leading to too effective hacking of systems where the costs of getting it wrong can be catastrophic.

Or, to put more words on it: Misaligned incentives encourage local optimization, and that’s not a good proxy for societal optimization. This encourages hacking, which now generates greater harm than at any point in the past because the amount of damage that can result from local optimization is greater than at any point in the past.

OK, let’s get back to the notion of democracy as an information system. It’s not just democracy: Any form of governance is an information system. It’s a process that turns individual beliefs and preferences into group policy decisions. And, it uses feedback mechanisms to determine how well those decisions are working and then makes corrections accordingly.

Historically, there are many ways to do this. We can have a system where no one’s preference matters except the monarch’s or the nobles’ or the landowners’. Sometimes the stronger army gets to decide—or the people with the money.

Or we could tally up everyone’s preferences and do the thing that at least half of the people want. That’s basically the promise of democracy today, at its ideal. Parliamentary systems are better, but only in the margins—and it all feels kind of primitive. Lots of people write about how informationally poor elections are at aggregating individual preferences. It also results in all these misaligned incentives.

I realize that democracy serves different functions. Peaceful transition of power, minimizing harm, equality, fair decision making, better outcomes. I am taking for granted that democracy is good for all those things. I’m focusing on how we implement it.

Modern democracy uses elections to determine who represents citizens in the decision-making process. And all sorts of other ways to collect information about what people think and want, and how well policies are working. These are opinion polls, public comments to rule-making, advocating, lobbying, protesting and so on. And, in reality, it’s been hacked so badly that it does a terrible job of executing on the will of the people, creating further incentives to hack these systems.

To be fair, the democratic republic was the best form of government that mid 18th century technology could invent. Because communications and travel were hard, we needed to choose one of us to go all the way over there and pass laws in our name. It was always a coarse approximation of what we wanted. And our principles, values, conceptions of fairness; our ideas about legitimacy and authority have evolved a lot since the mid 18th century. Even the notion of optimal group outcomes depended on who was considered in the group and who was out.

But democracy is not a static system, it’s an aspirational direction. One that really requires constant improvement. And our democratic systems have not evolved at the same pace that our technologies have. Blocking progress in democracy is itself a hack of democracy.

Today we have much better technology that we can use in the service of democracy. Surely there are better ways to turn individual preferences into group policies. Now that communications and travel are easy. Maybe we should assign representation by age, or profession or randomly by birthday. Maybe we can invent an AI that calculates optimal policy outcomes based on everyone’s preferences.

Whatever we do, we need systems that better align individual and group incentives, at all scales. Systems designed to be resistant to hacking. And resilient to catastrophic risks. Systems that leverage cooperation more and conflict less. And are not zero-sum.

Why can’t we have a game where everybody wins?

This has never been done before. It’s not capitalism, it’s not communism, it’s not socialism. It’s not current democracies or autocracies. It would be unlike anything we’ve ever seen.

Some of this comes down to how trust and cooperation work. When I wrote “Liars and Outliers” in 2012, I wrote about four systems for enabling trust: our innate morals, concern about our reputations, the laws we live under and security technologies that constrain our behavior. I wrote about how the first two are more informal than the last two. And how the last two scale better, and allow for larger and more complex societies. They enable cooperation amongst strangers.

What I didn’t appreciate is how different the first and last two are. Morals and reputation are both old biological systems of trust. They’re person to person, based on human connection and cooperation. Laws—and especially security technologies—are newer systems of trust that force us to cooperate. They’re socio-technical systems. They’re more about confidence and control than they are about trust. And that allows them to scale better. Taxi driver used to be one of the country’s most dangerous professions. Uber changed that through pervasive surveillance. My Uber driver and I don’t know or trust each other, but the technology lets us both be confident that neither of us will cheat or attack each other. Both drivers and passengers compete for star rankings, which align local and global incentives.

In today’s tech-mediated world, we are replacing the rituals and behaviors of cooperation with security mechanisms that enforce compliance. And innate trust in people with compelled trust in processes and institutions. That scales better, but we lose the human connection. It’s also expensive, and becoming even more so as our power grows. We need more security for these systems. And the results are much easier to hack.

But here’s the thing: Our informal human systems of trust are inherently unscalable. So maybe we have to rethink scale.

Our 18th century systems of democracy were the only things that scaled with the technology of the time. Imagine a group of friends deciding where to have dinner. One is kosher, one is a vegetarian. They would never use a winner-take-all ballot to decide where to eat. But that’s a system that scales to large groups of strangers.

Scale matters more broadly in governance as well. We have global systems of political and economic competition. On the other end of the scale, the most common form of governance on the planet is socialism. It’s how families function: people work according to their abilities, and resources are distributed according to their needs.

I think we need governance that is both very large and very small. Our catastrophic technological risks are planetary-scale: climate change, AI, internet, bio-tech. And we have all the local problems inherent in human societies. We have very few problems anymore that are the size of France or Virginia. Some systems of governance work well on a local level but don’t scale to larger groups. But now that we have more technology, we can make other systems of democracy scale.

This runs headlong into historical norms about sovereignty. But that’s already becoming increasingly irrelevant. The modern concept of a nation arose around the same time as the modern concept of democracy. But constituent boundaries are now larger and more fluid, and depend a lot on context. It makes no sense that the decisions about the “drug war”—or climate migration—are delineated by nation. The issues are much larger than that. Right now there is no governance body with the right footprint to regulate Internet platforms like Facebook. Which has more users world-wide than Christianity.

We also need to rethink growth. Growth only equates to progress when the resources necessary to grow are cheap and abundant. Growth is often extractive. And at the expense of something else. Growth is how we fuel our zero-sum systems. If the pie gets bigger, it’s OK that we waste some of the pie in order for it to grow. That doesn’t make sense when resources are scarce and expensive. Growing the pie can end up costing more than the increase in pie size. Sustainability makes more sense. And a metric more suited to the environment we’re in right now.

Finally, agility is also important. Back to systems theory, governance is an attempt to control complex systems with complicated systems. This gets harder as the systems get larger and more complex. And as catastrophic risk raises the costs of getting it wrong.
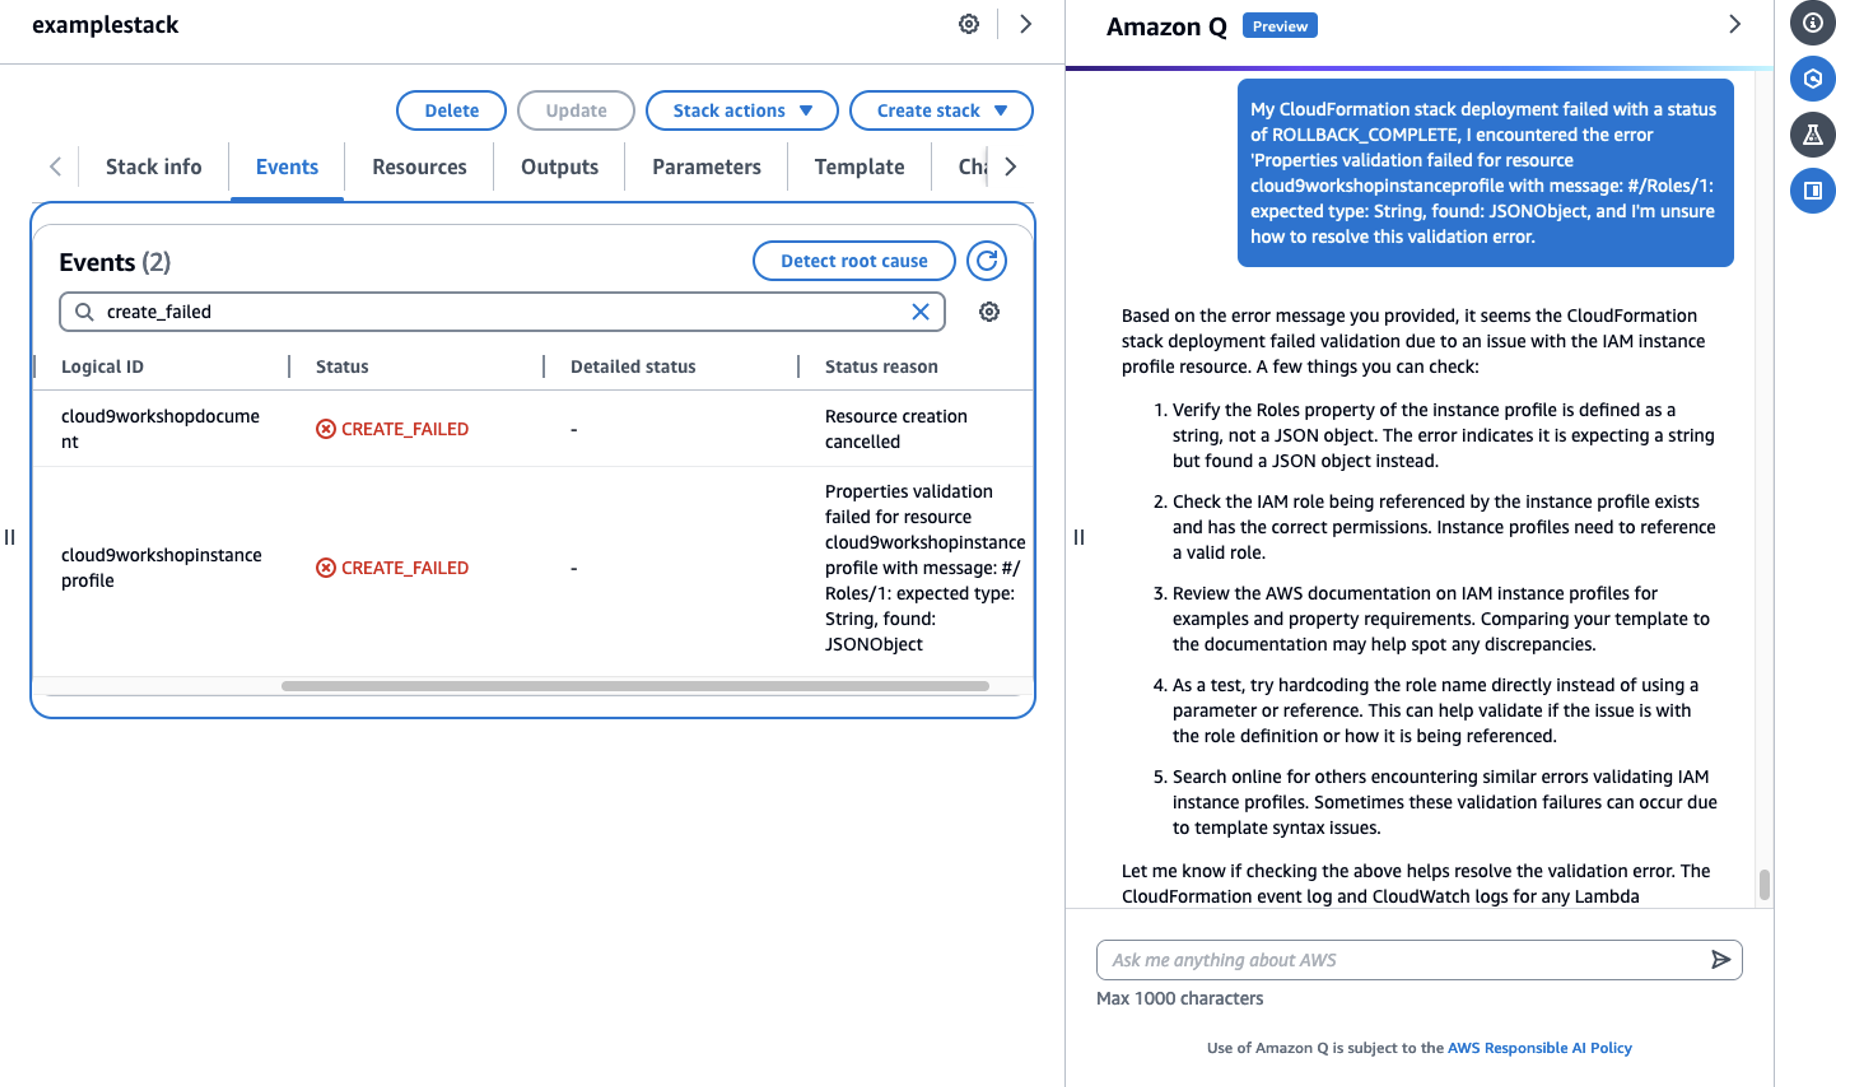
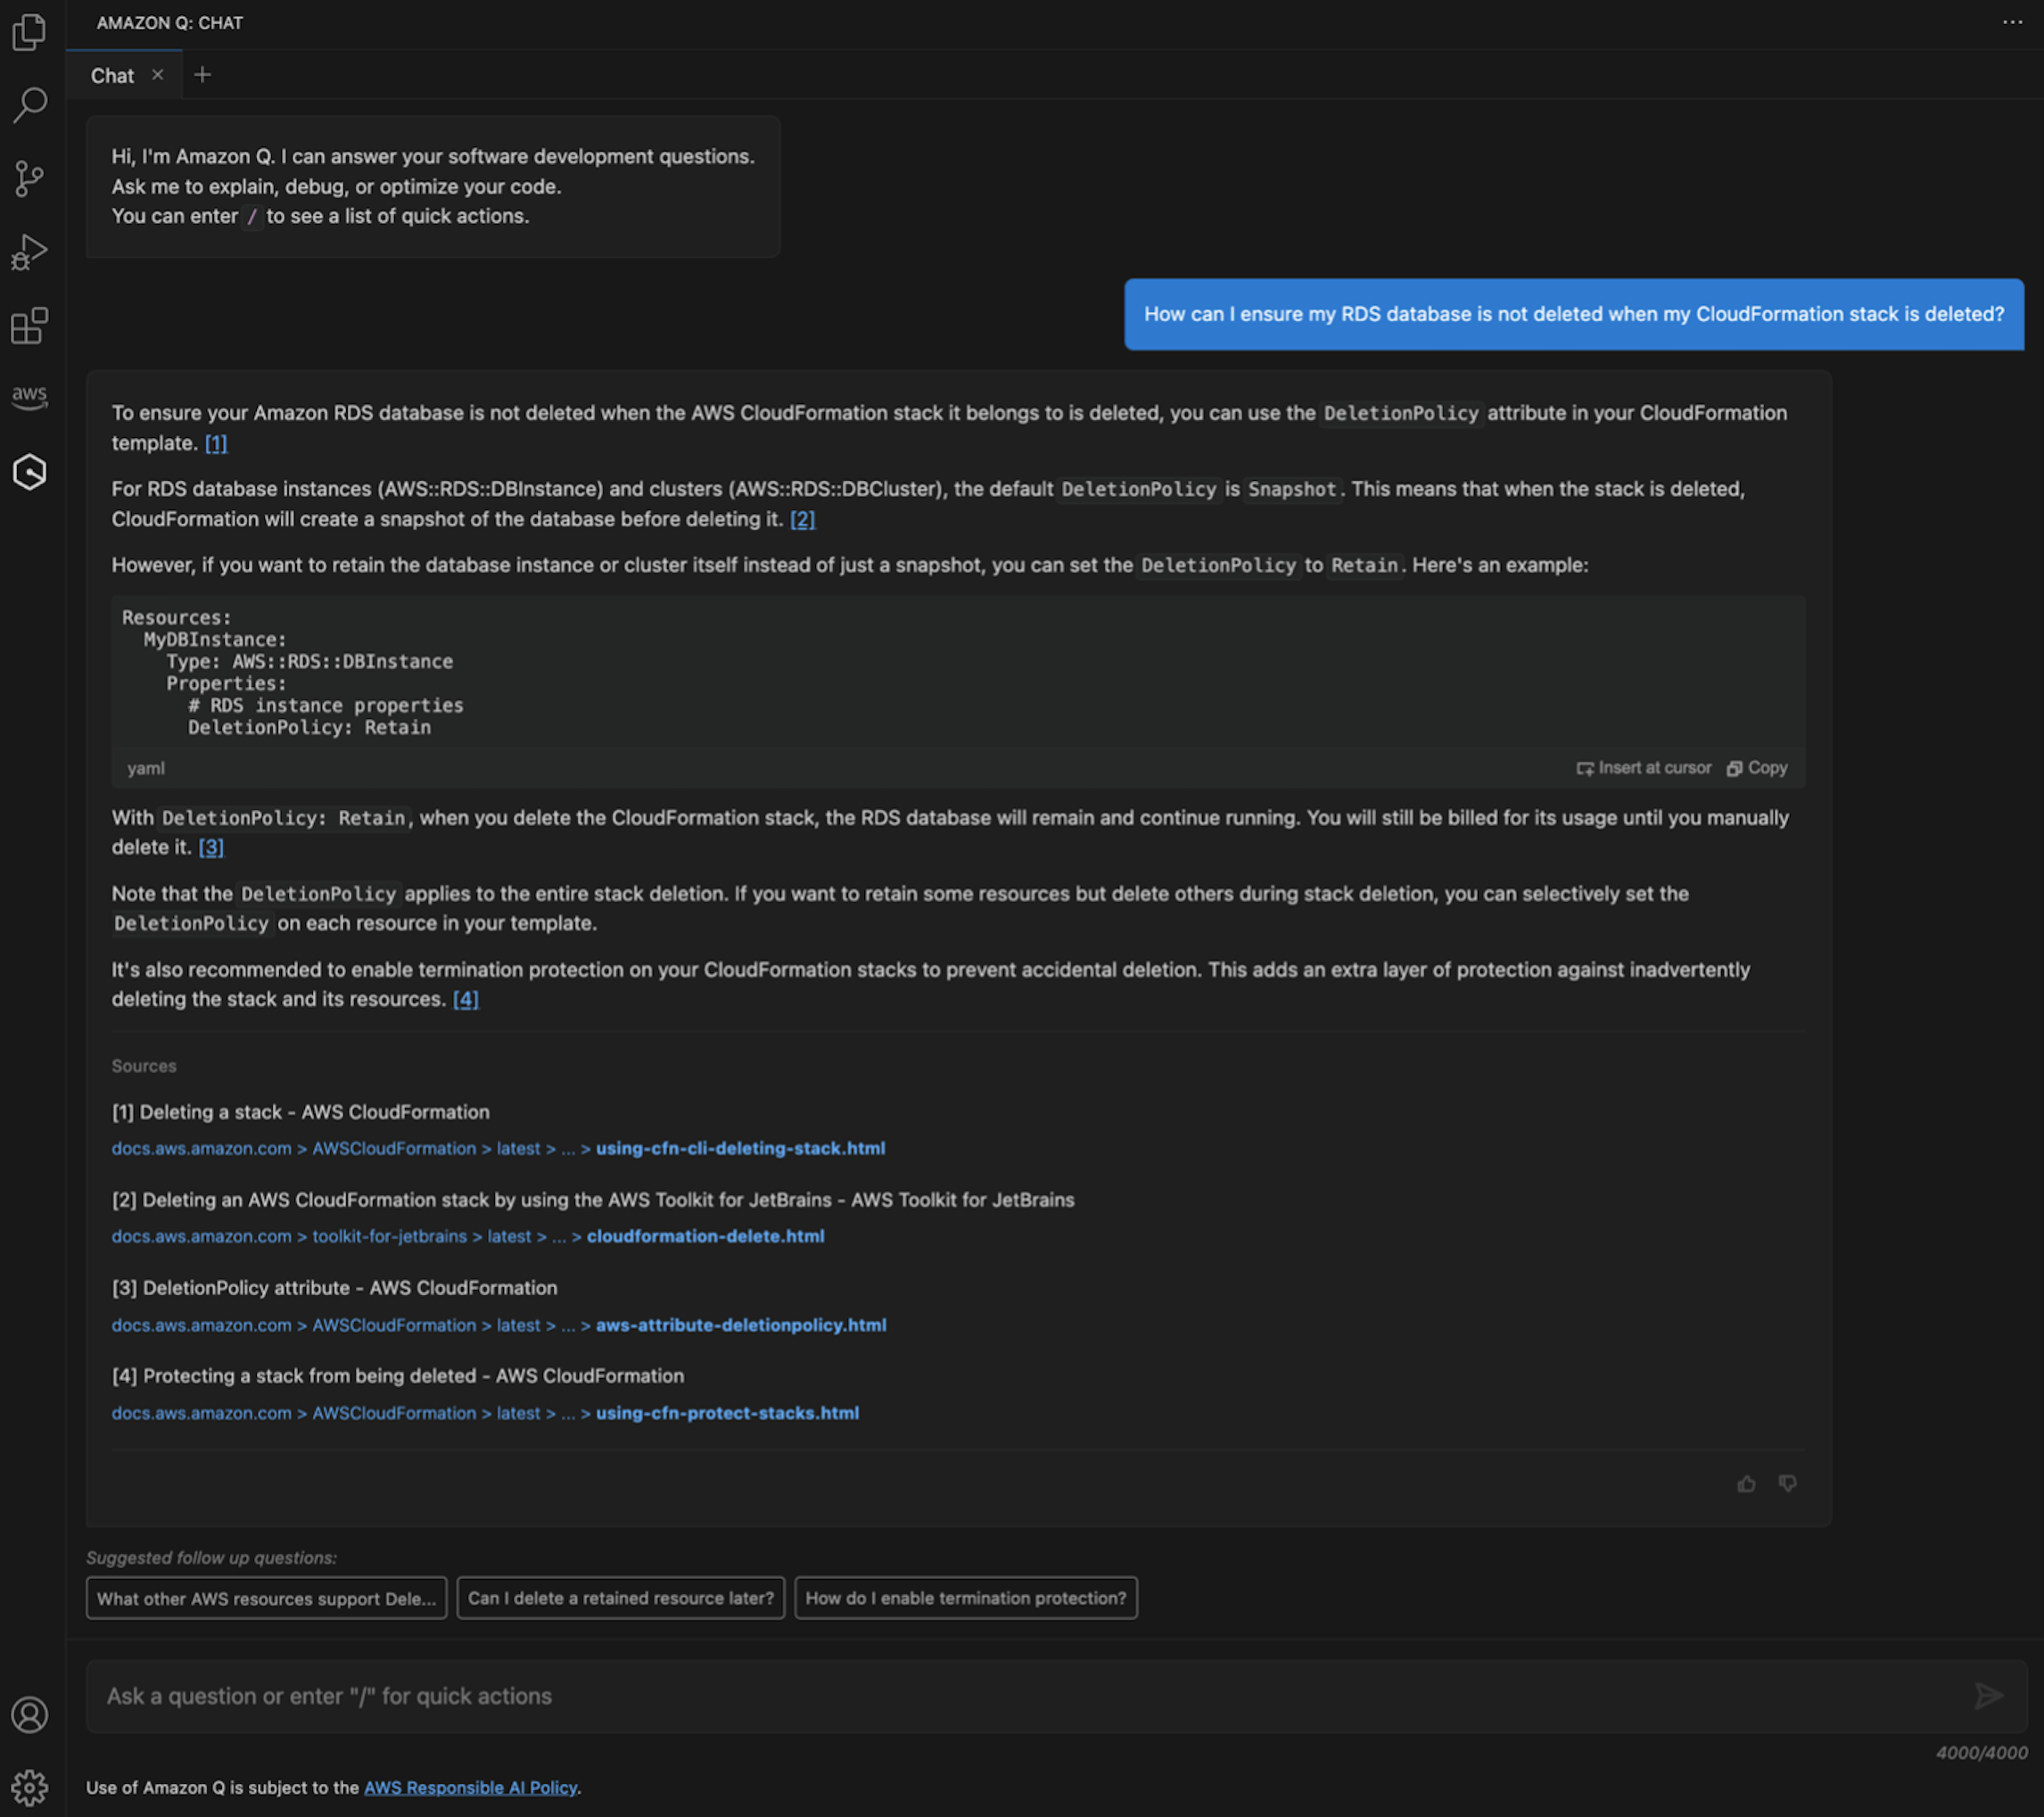
In recent decades, we have replaced the richness of human interaction with economic models. Models that turn everything into markets. Market fundamentalism scaled better, but the social cost was enormous. A lot of how we think and act isn’t captured by those models. And those complex models turn out to be very hackable. Increasingly so at larger scales.

Lots of people have written about the speed of technology versus the speed of policy. To relate it to this talk: Our human systems of governance need to be compatible with the technologies they’re supposed to govern. If they’re not, eventually the technological systems will replace the governance systems. Think of Twitter as the de facto arbiter of free speech.

This means that governance needs to be agile. And able to quickly react to changing circumstances. Imagine a court saying to Peter Thiel: “Sorry. That’s not how Roth IRAs are supposed to work. Now give us our tax on that $5B.” This is also essential in a technological world: one that is moving at unprecedented speeds, where getting it wrong can be catastrophic and one that is resource constrained. Agile patching is how we maintain security in the face of constant hacking—and also red teaming. In this context, both journalism and civil society are important checks on government.

I want to quickly mention two ideas for democracy, one old and one new. I’m not advocating for either. I’m just trying to open you up to new possibilities. The first is sortition. These are citizen assemblies brought together to study an issue and reach a policy decision. They were popular in ancient Greece and Renaissance Italy, and are increasingly being used today in Europe. The only vestige of this in the U.S. is the jury. But you can also think of trustees of an organization. The second idea is liquid democracy. This is a system where everybody has a proxy that they can transfer to someone else to vote on their behalf. Representatives hold those proxies, and their vote strength is proportional to the number of proxies they have. We have something like this in corporate proxy governance.

Both of these are algorithms for converting individual beliefs and preferences into policy decisions. Both of these are made easier through 21st century technologies. They are both democracies, but in new and different ways. And while they’re not immune to hacking, we can design them from the beginning with security in mind.

This points to technology as a key component of any solution. We know how to use technology to build systems of trust. Both the informal biological kind and the formal compliance kind. We know how to use technology to help align incentives, and to defend against hacking.

We talked about AI hacking; AI can also be used to defend against hacking, finding vulnerabilities in computer code, finding tax loopholes before they become law and uncovering attempts at surreptitious micro-legislation.

Think back to democracy as an information system. Can AI techniques be used to uncover our political preferences and turn them into policy outcomes, get feedback and then iterate? This would be more accurate than polling. And maybe even elections. Can an AI act as our representative? Could it do a better job than a human at voting the preferences of its constituents?

Can we have an AI in our pocket that votes on our behalf, thousands of times a day, based on the preferences it infers we have. Or maybe based on the preferences it infers we would have if we read up on the issues and weren’t swayed by misinformation. It’s just another algorithm for converting individual preferences into policy decisions. And it certainly solves the problem of people not paying attention to politics.

But slow down: This is rapidly devolving into technological solutionism. And we know that doesn’t work.

A general question to ask here is when do we allow algorithms to make decisions for us? Sometimes it’s easy. I’m happy to let my thermostat automatically turn my heat on and off or to let an AI drive a car or optimize the traffic lights in a city. I’m less sure about an AI that sets tax rates, or corporate regulations or foreign policy. Or an AI that tells us that it can’t explain why, but strongly urges us to declare war—right now. Each of these is harder because they are more complex systems: non-local, multi-agent, long-duration and so on. I also want any AI that works on my behalf to be under my control. And not controlled by a large corporate monopoly that allows me to use it.

And learned helplessness is an important consideration. We’re probably OK with no longer needing to know how to drive a car. But we don’t want a system that results in us forgetting how to run a democracy. Outcomes matter here, but so do mechanisms. Any AI system should engage individuals in the process of democracy, not replace them.

So while an AI that does all the hard work of governance might generate better policy outcomes. There is social value in a human-centric political system, even if it is less efficient. And more technologically efficient preference collection might not be better, even if it is more accurate.

Procedure and substance need to work together. There is a role for AI in decision making: moderating discussions, highlighting agreements and disagreements helping people reach consensus. But it is an independent good that we humans remain engaged in—and in charge of—the process of governance.

And that value is critical to making democracy function. Democratic knowledge isn’t something that’s out there to be gathered: It’s dynamic; it gets produced through the social processes of democracy. The term of art is “preference formation.” We’re not just passively aggregating preferences, we create them through learning, deliberation, negotiation and adaptation. Some of these processes are cooperative and some of these are competitive. Both are important. And both are needed to fuel the information system that is democracy.

We’re never going to remove conflict and competition from our political and economic systems. Human disagreement isn’t just a surface feature; it goes all the way down. We have fundamentally different aspirations. We want different ways of life. I talked about optimal policies. Even that notion is contested: optimal for whom, with respect to what, over what time frame? Disagreement is fundamental to democracy. We reach different policy conclusions based on the same information. And it’s the process of making all of this work that makes democracy possible.

So we actually can’t have a game where everybody wins. Our goal has to be to accommodate plurality, to harness conflict and disagreement, and not to eliminate it. While, at the same time, moving from a player-versus-player game to a player-versus-environment game.

There’s a lot missing from this talk. Like what these new political and economic governance systems should look like. Democracy and capitalism are intertwined in complex ways, and I don’t think we can recreate one without also recreating the other. My comments about agility lead to questions about authority and how that interplays with everything else. And how agility can be hacked as well. We haven’t even talked about tribalism in its many forms. In order for democracy to function, people need to care about the welfare of strangers who are not like them. We haven’t talked about rights or responsibilities. What is off limits to democracy is a huge discussion. And Butterin’s trilemma also matters here: that you can’t simultaneously build systems that are secure, distributed, and scalable.

I also haven’t given a moment’s thought to how to get from here to there. Everything I’ve talked about—incentives, hacking, power, complexity—also applies to any transition systems. But I think we need to have unconstrained discussions about what we’re aiming for. If for no other reason than to question our assumptions. And to imagine the possibilities. And while a lot of the AI parts are still science fiction, they’re not far-off science fiction.

I know we can’t clear the board and build a new governance structure from scratch. But maybe we can come up with ideas that we can bring back to reality.

To summarize, the systems of governance we designed at the start of the Industrial Age are ill-suited to the Information Age. Their incentive structures are all wrong. They’re insecure and they’re wasteful. They don’t generate optimal outcomes. At the same time we’re facing catastrophic risks to society due to powerful technologies. And a vastly constrained resource environment. We need to rethink our systems of governance; more cooperation and less competition and at scales that are suited to today’s problems and today’s technologies. With security and precautions built in. What comes after democracy might very well be more democracy, but it will look very different.

This feels like a challenge worthy of our security expertise.

This text is the transcript from a keynote speech delivered during the RSA Conference in San Francisco on April 25, 2023. It was previously published in Cyberscoop. I thought I posted it to my blog and Crypto-Gram last year, but it seems that I didn’t.

AWS Weekly Roundup: Passkey MFA, Malware Protection on Amazon S3, and more (June 17, 2024)

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-passkey-mfa-malware-protection-on-amazon-s3-and-more-june-17-2024/

Last week, my alma mater Standard Bank Group (SBG) hosted a Software Engineering Conference and invited me to be one of the keynote speakers. SBG has presence throughout Africa and this hybrid conference was attended by almost 2,000 engineers from across the continent. It was amazing to reconnect with long-time friends and former colleagues, and to make new friends.

Last week’s launches
Here are some launches that got my attention during the previous week.

Passkey multi-factor authentication (MFA) for root and IAM users – We’ve added passkeys to the list of supported multi-factor authentication (MFA) for your root and AWS Identity and Access Management (IAM) users, to give you the convenience of use and easy recoverability. A passkey is a pair of cryptographic keys generated on your client device when you register for a service or a website. Passkeys can be used to replace passwords. However, for this initial release, we choose to use passkeys as a second factor authentication, in addition to your password.

Amazon GuardDuty Malware Protection for Amazon S3 – At AWS re:Inforce 2024 this past week, we announced general availability of Amazon GuardDuty Malware Protection for Amazon Simple Storage Service (Amazon S3). This is an expansion of GuardDuty Malware Protection to detect malicious file uploads to selected S3 buckets. Benefits include the ability to fully manage malware detection without managing compute infrastructure, and coverage summary for all protected buckets in your organization, to name a few. Read more in the post published last week detailing Amazon GuardDuty Malware Protection for Amazon S3.

IAM Access Analyzer Update – More goodness out of AWS re:Inforce 2024 last week! We announced an IAM Access Analyzer Update, which allows you to extend custom policy checks and also includes a guided revocation. This gives you guidance that you can share with your developers so that they can revoke unneeded permissions. My colleague Jeff Barr writes about it in more detail in this post.

Other AWS news
AWS open source news and updates – My colleague Ricardo writes this weekly open source newsletter in which he highlights new open source projects, tools, and demos from the AWS Community.

The .Net developer community remains close to our hearts here at AWS. I’m inspired by my colleagues Brandon Minnick and Francois Bouteruche who support this community, resulting in the AWS and the Azure engineering teams working together to create delightful .NET developer experiences. At the recently held NDC Oslo, which is part of the NDC Conferences hosted around the world, VP of Azure Developer Experience, Scott Hunter, talked about this collaboration during his keynote. Make sure to catch the keynote on the NDC Conferences YouTube Channel as soon as it’s published.

Upcoming AWS events
AWS Summits – These are free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Whether you’re in the Americas, Asia Pacific & Japan, or EMEA region, learn here about future AWS Summit events happening in your area.

AWS Community Days – Join an AWS Community Day event just like the one I mentioned at the beginning of this post to participate in technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from your area. If you’re in Sri Lanka, there’s an event happening in your area next week.

You can browse all upcoming in-person and virtual events here.

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Veliswa

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS.