AI agents are now hacking computers. They’re getting better at all phases of cyberattacks, faster than most of us expected. They can chain together different aspects of a cyber operation, and hack autonomously, at computer speeds and scale. This is going to change everything.
Over the summer, hackers proved the concept, industry institutionalized it, and criminals operationalized it. In June, AI company XBOW took the top spot on HackerOne’s US leaderboard after submitting over 1,000 new vulnerabilities in just a few months. In August, the seven teams competing in DARPA’s AI Cyber Challenge collectively found 54 new vulnerabilities in a target system, in four hours (of compute). Also in August, Google announced that its Big Sleep AI found dozens of new vulnerabilities in open-source projects.
It gets worse. In July Ukraine’s CERT discovered a piece of Russian malware that used an LLM to automate the cyberattack process, generating both system reconnaissance and data theft commands in real-time. In August, Anthropic reported that they disrupted a threat actor that used Claude, Anthropic’s AI model, to automate the entire cyberattack process. It was an impressive use of the AI, which performed network reconnaissance, penetrated networks, and harvested victims’ credentials. The AI was able to figure out which data to steal, how much money to extort out of the victims, and how to best write extortion emails.
Another hacker used Claude to create and market his own ransomware, complete with “advanced evasion capabilities, encryption, and anti-recovery mechanisms.” And in September, Checkpoint reported on hackers using HexStrike-AI to create autonomous agents that can scan, exploit, and persist inside target networks. Also in September, a research team showed how they can quickly and easily reproduce hundreds of vulnerabilities from public information. These tools are increasingly free for anyone to use. Villager, a recently released AI pentesting tool from Chinese company Cyberspike, uses the Deepseek model to completely automate attack chains.
This is all well beyond AIs capabilities in 2016, at DARPA’s Cyber Grand Challenge. The annual Chinese AI hacking challenge, Robot Hacking Games, might be on this level, but little is known outside of China.
Tipping point on the horizon
AI agents now rival and sometimes surpass even elite human hackers in sophistication. They automate operations at machine speed and global scale. The scope of their capabilities allows these AI agents to completely automate a criminal’s command to maximize profit, or structure advanced attacks to a government’s precise specifications, such as to avoid detection.
In this future, attack capabilities could accelerate beyond our individual and collective capability to handle. We have long taken it for granted that we have time to patch systems after vulnerabilities become known, or that withholding vulnerability details prevents attackers from exploiting them. This is no longer the case.
The cyberattack/cyberdefense balance has long skewed towards the attackers; these developments threaten to tip the scales completely. We’re potentiallylooking at a singularity event for cyber attackers. Key parts of the attack chain are becoming automated and integrated: persistence, obfuscation, command-and-control, and endpoint evasion. Vulnerability research could potentially be carried out during operations instead of months in advance.
The most skilled will likely retain an edge for now. But AI agents don’t have to be better at a human task in order to be useful. They just have to excel in one of four dimensions: speed, scale, scope, or sophistication. But there is every indication that they will eventually excel at all four. By reducing the skill, cost, and time required to find and exploit flaws, AI can turn rare expertise into commodity capabilities and gives average criminals an outsized advantage.
The AI-assisted evolution of cyberdefense
AI technologies can benefit defenders as well. We don’t know how the different technologies of cyber-offense and cyber-defense will be amenable to AI enhancement, but we can extrapolate a possible series of overlapping developments.
Phase One: The Transformation of the Vulnerability Researcher. AI-based hacking benefits defenders as well as attackers. In this scenario, AI empowers defenders to do more. It simplifies capabilities, providing far more people the ability to perform previously complex tasks, and empowers researchers previously busy with these tasks to accelerate or move beyond them, freeing time to work on problems that require human creativity. History suggests a pattern. Reverse engineering was a laborious manual process until tools such as IDA Pro made the capability available to many. AI vulnerability discovery could follow a similar trajectory, evolving through scriptable interfaces, automated workflows, and automated research before reaching broad accessibility.
Phase Two: The Emergence of VulnOps. Between research breakthroughs and enterprise adoption, a new discipline might emerge: VulnOps. Large research teams are already building operational pipelines around their tooling. Their evolution could mirror how DevOps professionalized software delivery. In this scenario, specialized research tools become developer products. These products may emerge as a SaaS platform, or some internal operational framework, or something entirely different. Think of it as AI-assisted vulnerability research available to everyone, at scale, repeatable, and integrated into enterprise operations.
Phase Three: The Disruption of the Enterprise Software Model. If enterprises adopt AI-powered security the way they adopted continuous integration/continuous delivery (CI/CD), several paths open up. AI vulnerability discovery could become a built-in stage in delivery pipelines. We can envision a world where AI vulnerability discovery becomes an integral part of the software development process, where vulnerabilities are automatically patched even before reaching production—a shift we might call continuous discovery/continuous repair (CD/CR). Third-party risk management (TPRM) offers a natural adoption route, lower-risk vendor testing, integration into procurement and certification gates, and a proving ground before wider rollout.
Phase Four: The Self-Healing Network. If organizations can independently discover and patch vulnerabilities in running software, they will not have to wait for vendors to issue fixes. Building in-house research teams is costly, but AI agents could perform such discovery and generate patches for many kinds of code, including third-party and vendor products. Organizations may develop independent capabilities that create and deploy third-party patches on vendor timelines, extending the current trend of independent open-source patching. This would increase security, but having customers patch software without vendor approval raises questions about patch correctness, compatibility, liability, right-to-repair, and long-term vendor relationships.
These are all speculations. Maybe AI-enhanced cyberattacks won’t evolve the ways we fear. Maybe AI-enhanced cyberdefense will give us capabilities we can’t yet anticipate. What will surprise us most might not be the paths we can see, but the ones we can’t imagine yet.
This essay was written with Heather Adkins and Gadi Evron, and originally appeared in CSO.
As a serverless cloud provider, we run your code on our globally distributed infrastructure. Being able to run customer code on our network means that anyone can take advantage of our global presence and low latency. Workers isn’t just efficient though, we also make it simple for our users. In short: You write code. We handle the rest.
Part of ‘handling the rest’ is making Workers as secure as possible. We have previously written about our security architecture. Making Workers secure is an interesting problem because the whole point of Workers is that we are running third party code on our hardware. This is one of the hardest security problems there is: any attacker has the full power available of a programming language running on the victim’s system when they are crafting their attacks.
This is why we are constantly updating and improving the Workers Runtime to take advantage of the latest improvements in both hardware and software. This post shares some of the latest work we have been doing to keep Workers secure.
Some background first: Workers is built around the V8 JavaScript runtime, originally developed for Chromium-based browsers like Chrome. This gives us a head start, because V8 was forged in an adversarial environment, where it has always been under intense attack and scrutiny. Like Workers, Chromium is built to run adversarial code safely. That’s why V8 is constantly being tested against the best fuzzers and sanitizers, and over the years, it has been hardened with new technologies like Oilpan/cppgc and improved static analysis.
We use V8 in a slightly different way, though, so we will be describing in this post how we have been making some changes to V8 to improve security in our use case.
Hardware-assisted security improvements from Memory Protection Keys
Modern CPUs from Intel, AMD, and ARM have support for memory protection keys, sometimes called PKU, Protection Keys for Userspace. This is a great security feature which increases the power of virtual memory and memory protection.
Traditionally, the memory protection features of the CPU in your PC or phone were mainly used to protect the kernel and to protect different processes from each other. Within each process, all threads had access to the same memory. Memory protection keys allow us to prevent specific threads from accessing memory regions they shouldn’t have access to.
V8 already uses memory protection keys for the JIT compilers. The JIT compilers for a language like JavaScript generate optimized, specialized versions of your code as it runs. Typically, the compiler is running on its own thread, and needs to be able to write data to the code area in order to install its optimized code. However, the compiler thread doesn’t need to be able to run this code. The regular execution thread, on the other hand, needs to be able to run, but not modify, the optimized code. Memory protection keys offer a way to give each thread the permissions it needs, but no more. And the V8 team in the Chromium project certainly aren’t standing still. They describe some of their future plans for memory protection keys here.
In Workers, we have some different requirements than Chromium. The security architecture for Workers uses V8 isolates to separate different scripts that are running on our servers. (In addition, we have extra mitigations to harden the system against Spectre attacks). If V8 is working as intended, this should be enough, but we believe in defense in depth: multiple, overlapping layers of security controls.
That’s why we have deployed internal modifications to V8 to use memory protection keys to isolate the isolates from each other. There are up to 15 different keys available on a modern x64 CPU and a few are used for other purposes in V8, so we have about 12 to work with. We give each isolate a random key which is used to protect its V8 heap data, the memory area containing the JavaScript objects a script creates as it runs. This means security bugs that might previously have allowed an attacker to read data from a different isolate would now hit a hardware trap in 92% of cases. (Assuming 12 keys, 92% is about 11/12.)
The illustration shows an attacker attempting to read from a different isolate. Most of the time this is detected by the mismatched memory protection key, which kills their script and notifies us, so we can investigate and remediate. The red arrow represents the case where the attacker got lucky by hitting an isolate with the same memory protection key, represented by the isolates having the same colors.
However, we can further improve on a 92% protection rate. In the last part of this blog post we’ll explain how we can lift that to 100% for a particular common scenario. But first, let’s look at a software hardening feature in V8 that we are taking advantage of.
The V8 sandbox, a software-based security boundary
Over the past few years, V8 has been gaining another defense in depth feature: the V8 sandbox. (Not to be confused with the layer 2 sandbox which Workers have been using since the beginning.) The V8 sandbox has been a multi-year project that has been gaining maturity for a while. The sandbox project stems from the observation that many V8 security vulnerabilities start by corrupting objects in the V8 heap memory. Attackers then leverage this corruption to reach other parts of the process, giving them the opportunity to escalate and gain more access to the victim’s browser, or even the entire system.
V8’s sandbox project is an ambitious software security mitigation that aims to thwart that escalation: to make it impossible for the attacker to progress from a corruption on the V8 heap to a compromise of the rest of the process. This means, among other things, removing all pointers from the heap. But first, let’s explain in as simple terms as possible, what a memory corruption attack is.
Memory corruption attacks
A memory corruption attack tricks a program into misusing its own memory. Computer memory is just a store of integers, where each integer is stored in a location. The locations each have an address, which is also just a number. Programs interpret the data in these locations in different ways, such as text, pixels, or pointers. Pointers are addresses that identify a different memory location, so they act as a sort of arrow that points to some other piece of data.
Here’s a concrete example, which uses a buffer overflow. This is a form of attack that was historically common and relatively simple to understand: Imagine a program has a small buffer (like a 16-character text field) followed immediately by an 8-byte pointer to some ordinary data. An attacker might send the program a 24-character string, causing a “buffer overflow.” Because of a vulnerability in the program, the first 16 characters fill the intended buffer, but the remaining 8 characters spill over and overwrite the adjacent pointer.
See below for how such an attack would now be thwarted.
Now the pointer has been redirected to point at sensitive data of the attacker’s choosing, rather than the normal data it was originally meant to access. When the program tries to use what it believes is its normal pointer, it’s actually accessing sensitive data chosen by the attacker.
This type of attack works in steps: first create a small confusion (like the buffer overflow), then use that confusion to create bigger problems, eventually gaining access to data or capabilities the attacker shouldn’t have. The attacker can eventually use the misdirection to either steal information or plant malicious data that the program will treat as legitimate.
This was a somewhat abstract description of memory corruption attacks using a buffer overflow, one of the simpler techniques. For some much more detailed and recent examples, see this description from Google, or this breakdown of a V8 vulnerability.
Compressed pointers in V8
Many attacks are based on corrupting pointers, so ideally we would remove all pointers from the memory of the program. Since an object-oriented language’s heap is absolutely full of pointers, that would seem, on its face, to be a hopeless task, but it is enabled by an earlier development. Starting in 2020, V8 has offered the option of saving memory by using compressed pointers. This means that, on a 64-bit system, the heap uses only 32 bit offsets, relative to a base address. This limits the total heap to maximally 4 GiB, a limitation that is acceptable for a browser, and also fine for individual scripts running in a V8 isolate on Cloudflare Workers.
An artificial object with various fields, showing how the layout differs in a compressed vs. an uncompressed heap. The boxes are 64 bits wide.
If the whole of the heap is in a single 4 GiB area then the first 32 bits of all pointers will be the same, and we don’t need to store them in every pointer field in every object. In the diagram we can see that the object pointers all start with 0x12345678, which is therefore redundant and doesn’t need to be stored. This means that object pointer fields and integer fields can be reduced from 64 to 32 bits.
We still need 64 bit fields for some fields like double precision floats and for the sandbox offsets of buffers, which are typically used by the script for input and output data. See below for details.
Integers in an uncompressed heap are stored in the high 32 bits of a 64 bit field. In the compressed heap, the top 31 bits of a 32 bit field are used. In both cases the lowest bit is set to 0 to indicate integers (as opposed to pointers or offsets).
Conceptually, we have two methods for compressing and decompressing, using a base address that is divisible by 4 GiB:
// Decompress a 32 bit offset to a 64 bit pointer by adding a base address.
void* Decompress(uint32_t offset) { return base + offset; }
// Compress a 64 bit pointer to a 32 bit offset by discarding the high bits.
uint32_t Compress(void* pointer) { return (intptr_t)pointer & 0xffffffff; }
This pointer compression feature, originally primarily designed to save memory, can be used as the basis of a sandbox.
From compressed pointers to the sandbox
The biggest 32-bit unsigned integer is about 4 billion, so the Decompress() function cannot generate any pointer that is outside the range [base, base + 4 GiB]. You could say the pointers are trapped in this area, so it is sometimes called the pointer cage. V8 can reserve 4 GiB of virtual address space for the pointer cage so that only V8 objects appear in this range. By eliminating all pointers from this range, and following some other strict rules, V8 can contain any memory corruption by an attacker to this cage. Even if an attacker corrupts a 32 bit offset within the cage, it is still only a 32 bit offset and can only be used to create new pointers that are still trapped within the pointer cage.
The buffer overflow attack from earlier no longer works because only the attacker’s own data is available in the pointer cage.
To construct the sandbox, we take the 4 GiB pointer cage and add another 4 GiB for buffers and other data structures to make the 8 GiB sandbox. This is why the buffer offsets above are 33 bits, so they can reach buffers in the second half of the sandbox (40 bits in Chromium with larger sandboxes). V8 stores these buffer offsets in the high 33 bits and shifts down by 31 bits before use, in case an attacker corrupted the low bits.
Cloudflare Workers have made use of compressed pointers in V8 for a while, but for us to get the full power of the sandbox we had to make some changes. Until recently, all isolates in a process had to be one single sandbox if you were using the sandboxed configuration of V8. This would have limited the total size of all V8 heaps to be less than 4 GiB, far too little for our architecture, which relies on serving 1000s of scripts at once.
That’s why we commissioned Igalia to add isolate groups to V8. Each isolate group has its own sandbox and can have 1 or more isolates within it. Building on this change we have been able to start using the sandbox, eliminating a whole class of potential security issues in one stroke. Although we can place multiple isolates in the same sandbox, we are currently only putting a single isolate in each sandbox.
The layout of the sandbox. In the sandbox there can be more than one isolate, but all their heap pages must be in the pointer cage: the first 4 GiB of the sandbox. Instead of pointers between the objects, we use 32 bit offsets. The offsets for the buffers are 33 bits, so they can reach the whole sandbox, but not outside it.
Virtual memory isn’t infinite, there’s a lot going on in a Linux process
At this point, we were not quite done, though. Each sandbox reserves 8 GiB of space in the virtual memory map of the process, and it must be 4 GiB aligned for efficiency. It uses much less physical memory, but the sandbox mechanism requires this much virtual space for its security properties. This presents us with a problem, since a Linux process ‘only’ has 128 TiB of virtual address space in a 4-level page table (another 128 TiB are reserved for the kernel, not available to user space).
At Cloudflare, we want to run Workers as efficiently as possible to keep costs and prices down, and to offer a generous free tier. That means that on each machine we have so many isolates running (one per sandbox) that it becomes hard to place them all in a 128 TiB space.
Knowing this, we have to place the sandboxes carefully in memory. Unfortunately, the Linux syscall, mmap, does not allow us to specify the alignment of an allocation unless you can guess a free location to request. To get an 8 GiB area that is 4 GiB aligned, we have to ask for 12 GiB, then find the aligned 8 GiB area that must exist within that, and return the unused (hatched) edges to the OS:
If we allow the Linux kernel to place sandboxes randomly, we end up with a layout like this with gaps. Especially after running for a while, there can be both 8 GiB and 4 GiB gaps between sandboxes:
Sadly, because of our 12 GiB alignment trick, we can’t even make use of the 8 GiB gaps. If we ask the OS for 12 GiB, it will never give us a gap like the 8 GiB gap between the green and blue sandboxes above. In addition, there are a host of other things going on in the virtual address space of a Linux process: the malloc implementation may want to grab pages at particular addresses, the executable and libraries are mapped at a random location by ASLR, and V8 has allocations outside the sandbox.
The latest generation of x64 CPUs supports a much bigger address space, which solves both problems, and Linux kernels are able to make use of the extra bits with five level page tables. A process has to opt into this, which is done by a single mmap call suggesting an address outside the 47 bit area. The reason this needs an opt-in is that some programs can’t cope with such high addresses. Curiously, V8 is one of them.
This isn’t hard to fix in V8, but not all of our fleet has been upgraded yet to have the necessary hardware. So for now, we need a solution that works with the existing hardware. We have modified V8 to be able to grab huge memory areas and then use mprotect syscalls to create tightly packed 8 GiB spaces for sandboxes, bypassing the inflexible mmap API.
Putting it all together
Taking control of the sandbox placement like this actually gives us a security benefit, but first we need to describe a particular threat model.
We assume for the purposes of this threat model that an attacker has an arbitrary way to corrupt data within the sandbox. This is historically the first step in many V8 exploits. So much so that there is a special tier in Google’s V8 bug bounty program where you may assume you have this ability to corrupt memory, and they will pay out if you can leverage that to a more serious exploit.
However, we assume that the attacker does not have the ability to execute arbitrary machine code. If they did, they could disable memory protection keys. Having access to the in-sandbox memory only gives the attacker access to their own data. So the attacker must attempt to escalate, by corrupting data inside the sandbox to access data outside the sandbox.
You will recall that the compressed, sandboxed V8 heap only contains 32 bit offsets. Therefore, no corruption there can reach outside the pointer cage. But there are also arrays in the sandbox — vectors of data with a given size that can be accessed with an index. In our threat model, the attacker can modify the sizes recorded for those arrays and the indexes used to access elements in the arrays. That means an attacker could potentially turn an array in the sandbox into a tool for accessing memory incorrectly. For this reason, the V8 sandbox normally has guard regions around it: These are 32 GiB virtual address ranges that have no virtual-to-physical address mappings. This helps guard against the worst case scenario: Indexing an array where the elements are 8 bytes in size (e.g. an array of double precision floats) using a maximal 32 bit index. Such an access could reach a distance of up to 32 GiB outside the sandbox: 8 times the maximal 32 bit index of four billion.
We want such accesses to trigger an alarm, rather than letting an attacker access nearby memory. This happens automatically with guard regions, but we don’t have space for conventional 32 GiB guard regions around every sandbox.
Instead of using conventional guard regions, we can make use of memory protection keys. By carefully controlling which isolate group uses which key, we can ensure that no sandbox within 32 GiB has the same protection key. Essentially, the sandboxes are acting as each other’s guard regions, protected by memory protection keys. Now we only need a wasted 32 GiB guard region at the start and end of the huge packed sandbox areas.
With the new sandbox layout, we use strictly rotating memory protection keys. Because we are not using randomly chosen memory protection keys, for this threat model the 92% problem described above disappears. Any in-sandbox security issue is unable to reach a sandbox with the same memory protection key. In the diagram, we show that there is no memory within 32 GiB of a given sandbox that has the same memory protection key. Any attempt to access memory within 32 GiB of a sandbox will trigger an alarm, just like it would with unmapped guard regions.
The future
In a way, this whole blog post is about things our customers don’t need to do. They don’t need to upgrade their server software to get the latest patches, we do that for them. They don’t need to worry whether they are using the most secure or efficient configuration. So there’s no call to action here, except perhaps to sleep easy.
However, if you find work like this interesting, and especially if you have experience with the implementation of V8 or similar language runtimes, then you should consider coming to work for us. We are recruiting both in the US and in Europe. It’s a great place to work, and Cloudflare is going from strength to strength.
Apple has introduced a new hardware/software security feature in the iPhone 17: “Memory Integrity Enforcement,” targeting the memory safety vulnerabilities that spyware products like Pegasus tend to use to get unauthorized system access. From Wired:
In recent years, a movement has been steadily growing across the global tech industry to address a ubiquitous and insidious type of bugs known as memory-safety vulnerabilities. A computer’s memory is a shared resource among all programs, and memory safety issues crop up when software can pull data that should be off limits from a computer’s memory or manipulate data in memory that shouldn’t be accessible to the program. When developers—even experienced and security-conscious developers—write software in ubiquitous, historic programming languages, like C and C++, it’s easy to make mistakes that lead to memory safety vulnerabilities. That’s why proactive tools like special programming languages have been proliferating with the goal of making it structurally impossible for software to contain these vulnerabilities, rather than attempting to avoid introducing them or catch all of them.
[…]
With memory-unsafe programming languages underlying so much of the world’s collective code base, Apple’s Security Engineering and Architecture team felt that putting memory safety mechanisms at the heart of Apple’s chips could be a deus ex machina for a seemingly intractable problem. The group built on a specification known as Memory Tagging Extension (MTE) released in 2019 by the chipmaker Arm. The idea was to essentially password protect every memory allocation in hardware so that future requests to access that region of memory are only granted by the system if the request includes the right secret.
Arm developed MTE as a tool to help developers find and fix memory corruption bugs. If the system receives a memory access request without passing the secret check, the app will crash and the system will log the sequence of events for developers to review. Apple’s engineers wondered whether MTE could run all the time rather than just being used as a debugging tool, and the group worked with Arm to release a version of the specification for this purpose in 2022 called Enhanced Memory Tagging Extension.
To make all of this a constant, real-time defense against exploitation of memory safety vulnerabilities, Apple spent years architecting the protection deeply within its chips so the feature could be on all the time for users without sacrificing overall processor and memory performance. In other words, you can see how generating and attaching secrets to every memory allocation and then demanding that programs manage and produce these secrets for every memory request could dent performance. But Apple says that it has been able to thread the needle.
Abstract: Large Language Model (LLM)-enabled agents are rapidly emerging across a wide range of applications, but their deployment introduces vulnerabilities with security implications. While prior work has examined prompt-based attacks (e.g., prompt injection) and data-oriented threats (e.g., data exfiltration), time-of-check to time-of-use (TOCTOU) remain largely unexplored in this context. TOCTOU arises when an agent validates external state (e.g., a file or API response) that is later modified before use, enabling practical attacks such as malicious configuration swaps or payload injection. In this work, we present the first study of TOCTOU vulnerabilities in LLM-enabled agents. We introduce TOCTOU-Bench, a benchmark with 66 realistic user tasks designed to evaluate this class of vulnerabilities. As countermeasures, we adapt detection and mitigation techniques from systems security to this setting and propose prompt rewriting, state integrity monitoring, and tool-fusing. Our study highlights challenges unique to agentic workflows, where we achieve up to 25% detection accuracy using automated detection methods, a 3% decrease in vulnerable plan generation, and a 95% reduction in the attack window. When combining all three approaches, we reduce the TOCTOU vulnerabilities from an executed trajectory from 12% to 8%. Our findings open a new research direction at the intersection of AI safety and systems security.
Vulnerabilities in electronic safes that use Securam Prologic locks:
While both their techniques represent glaring security vulnerabilities, Omo says it’s the one that exploits a feature intended as a legitimate unlock method for locksmiths that’s the more widespread and dangerous. “This attack is something where, if you had a safe with this kind of lock, I could literally pull up the code right now with no specialized hardware, nothing,” Omo says. “All of a sudden, based on our testing, it seems like people can get into almost any Securam Prologic lock in the world.”
[…]
Omo and Rowley say they informed Securam about both their safe-opening techniques in spring of last year, but have until now kept their existence secret because of legal threats from the company. “We will refer this matter to our counsel for trade libel if you choose the route of public announcement or disclosure,” a Securam representative wrote to the two researchers ahead of last year’s Defcon, where they first planned to present their research.
Only after obtaining pro bono legal representation from the Electronic Frontier Foundation’s Coders’ Rights Project did the pair decide to follow through with their plan to speak about Securam’s vulnerabilities at Defcon. Omo and Rowley say they’re even now being careful not to disclose enough technical detail to help others replicate their techniques, while still trying to offer a warning to safe owners about two different vulnerabilities that exist in many of their devices.
The company says that it plans on updating its locks by the end of the year, but have no plans to patch any locks already sold.
Attaullah Baig, WhatsApp’s former head of security, has filed a whistleblower lawsuit alleging that Facebook deliberately failed to fix a bunch of security flaws, in violation of its 2019 settlement agreement with the Federal Trade Commission.
The lawsuit, alleging violations of the whistleblower protection provision of the Sarbanes-Oxley Act passed in 2002, said that in 2022, roughly 100,000 WhatsApp users had their accounts hacked every day. By last year, the complaint alleged, as many as 400,000 WhatsApp users were getting locked out of their accounts each day as a result of such account takeovers.
Baig also allegedly notified superiors that data scraping on the platform was a problem because WhatsApp failed to implement protections that are standard on other messaging platforms, such as Signal and Apple Messages. As a result, the former WhatsApp head estimated that pictures and names of some 400 million user profiles were improperly copied every day, often for use in account impersonation scams.
On August 13, security researchers at Tel Aviv University disclosed a new HTTP/2 denial-of-service (DoS) vulnerability that they are calling MadeYouReset (CVE-2025-8671). This vulnerability exists in a limited number of unpatched HTTP/2 server implementations that do not sufficiently enforce restrictions on the number of times a client may send malformed frames. If you’re using Cloudflare for HTTP DDoS mitigation, you’re already protected from MadeYouReset.
Cloudflare was informed of this vulnerability in May through a coordinated disclosure process, and we were able to confirm that our systems were not susceptible, due in large part to the mitigations we put in place during Rapid Reset (CVE-2023-44487). MadeYouReset and Rapid Reset are two conceptually similar HTTP/2 protocol attacks that exploit a fundamental feature within the HTTP/2 specification: stream resets. In the HTTP/2 protocol, a “stream” represents an independent series of HTTP request/response pairs exchanged between the client and server within an HTTP/2 connection. The stream reset feature is intended to allow a client to initiate an HTTP request and subsequently cancel it before the server has delivered its response.
The vulnerability exploited by both MadeYouReset and Rapid Reset lies in the potential for malicious actors to abuse this stream reset mechanism. By repeatedly causing stream resets, attackers can overwhelm a server’s resources. While the server is attempting to process and respond to a multitude of requests, the rapid succession of resets forces it to expend computational effort on starting and then immediately discarding these operations. This can lead to resource exhaustion and impact the availability of the targeted server for legitimate users. The difference between MadeYouReset and Rapid Reset is that, instead of clients issuing stream resets directly, they instead trick servers into resetting streams by sending specially crafted malformed frames.
Fortunately, the MadeYouReset vulnerability only impacts a relatively small number of HTTP/2 implementations. In most major HTTP/2 implementations already in widespread use today, the proactive measures taken to counter Rapid Reset in 2023 have also provided substantial protection against MadeYouReset, limiting its potential impact and preventing a similarly disruptive event.
A note about Cloudflare’s Pingora and its users: Our open-sourced Pingora framework uses the popular Rust-language h2 library for its HTTP/2 support. Versions of h2 prior to 0.4.11 were potentially susceptible to MadeYouReset. Users of Pingora can patch their applications by updating their h2 crate version using the cargo update command. Pingora does not itself terminate inbound HTTP connections to Cloudflare’s network, meaning this vulnerability could not be exploited against Cloudflare’s infrastructure.
We would like to credit researchers Gal Bar Nahum, Anat Bremler-Barr, and Yaniv Harel of Tel Aviv University for discovering this vulnerability and thank them for their leadership in the coordinated disclosure process. Cloudflare always encourages security researchers to submit vulnerabilities like this to our HackerOne Bug Bounty program.
Google’s vulnerability finding team is again pushing the envelope of responsible disclosure:
Google’s Project Zero team will retain its existing 90+30 policy regarding vulnerability disclosures, in which it provides vendors with 90 days before full disclosure takes place, with a 30-day period allowed for patch adoption if the bug is fixed before the deadline.
However, as of July 29, Project Zero will also release limited details about any discovery they make within one week of vendor disclosure. This information will encompass:
The vendor or open-source project that received the report
The affected product
The date the report was filed and when the 90-day disclosure deadline expires
I have mixed feelings about this. On the one hand, I like that it puts more pressure on vendors to patch quickly. On the other hand, if no indication is provided regarding how severe a vulnerability is, it could easily cause unnecessary panic.
The problem is that Google is not a neutral vulnerability hunting party. To the extent that it finds, publishes, and reduces confidence in competitors’ products, Google benefits as a company.
Earlier this year, a group of external researchers identified and reported a vulnerability in Cloudflare’s SSL for SaaS v1 (Managed CNAME) product offering through Cloudflare’s bug bounty program. We officially deprecated SSL for SaaS v1 in 2021; however, some customers received extensions for extenuating circumstances that prevented them from migrating to SSL for SaaS v2 (Cloudflare for SaaS). We have continually worked with the remaining customers to migrate them onto Cloudflare for SaaS over the past four years and have successfully migrated the vast majority of these customers. For most of our customers, there is no action required; for the very small number of SaaS v1 customers, we will be actively working to help migrate you to SSL for SaaS v2 (Cloudflare for SaaS).
Background on SSL for SaaS v1 at Cloudflare
Back in 2017, Cloudflare announced SSL for SaaS, a product that allows SaaS providers to extend the benefits of Cloudflare security and performance to their end customers. Using a “Managed CNAME” configuration, providers could bring their customer’s domain onto Cloudflare. In the first version of SSL for SaaS (v1), the traffic for Custom Hostnames is proxied to the origin based on the IP addresses assigned to the zone. In this Managed CNAME configuration, the end customers simply pointed their domains to the SaaS provider origin using a CNAME record. The customer’s origin would then be configured to accept traffic from these hostnames.
What are the security concerns with v1 (Managed CNAME)?
While SSL for SaaS v1 enabled broad adoption of Cloudflare for end customer domains, its architecture introduced a subtle but important security risk – one that motivated us to build Cloudflare for SaaS.
As adoption scaled, so did our understanding of the security and operational limitations of SSL for SaaS v1. The architecture depended on IP-based routing and didn’t verify domain ownership before proxying traffic. That meant that any custom hostname pointed to the correct IP could be served through Cloudflare — even if ownership hadn’t been proven. While this produced the desired functionality, this design introduced risks and created friction when customers needed to make changes without downtime.
A malicious CF user aware of another customer’s Managed CNAME (via social engineering or publicly available info), could abuse the way SSL for SaaS v1 handles host header redirects through DNS manipulation and Man-in-The-Middle attack because of the way Cloudflare serves the valid TLS certificate for the Managed CNAME.
For regular connections to Cloudflare, the certificate served by Cloudflare is determined by the SNI provided by the client in the TLS handshake, while the zone configuration applied to a request is determined based on the host-header of the HTTP request.
In contrast, SSL for SaaS v1/Managed CNAME setups work differently. The certificate served by Cloudflare is still based on the TLS SNI, but the zone configuration is determined solely based on the specific Cloudflare anycast IP address the client connected to.
For example, let’s assume that 192.0.2.1 is the anycast IP address assigned to a SaaS provider. All connections to this IP address will be routed to the SaaS provider’s origin server, irrespective of the host-header in the HTTP request. This means that for the following request:
The certificate served by Cloudflare will be valid for www.cloudflare.com, but the request will not be sent to the origin server of www.cloudflare.com. It will instead be sent to the origin server of the SaaS provider assigned to the 192.0.2.1 IP address.
While the likelihood of exploiting this vulnerability is low and requires multiple complex conditions to be met, the vulnerability can be paired with other issues and potentially exploit other Cloudflare customers if:
The adversary is able to perform DNS poisoning on the target domain to change the IP address that the end-user connects to when visiting the target domain
The adversary is able to place a malicious payload on the Managed CNAME customer’s website, or discovers an existing cross-site scripting vulnerability on the website
Mitigation: A Phased Transition
To address these challenges, we launched SSL for SaaS v2 (Cloudflare for SaaS) and deprecated SSL for SaaS v1 in 2021. Cloudflare for SaaS transitioned away from IP-based routing towards a verified custom hostname model. Now, custom hostnames must pass a hostname verification step alongside SSL certificate validation to proxy to the customer origin. This improves security by limiting origin access to authorized hostnames and reduces downtime through hostname pre-validation, which allows customers to verify ownership before traffic is proxied through Cloudflare.
When Cloudflare for SaaS became generally available, we began a careful and deliberate deprecation of the original architecture. Starting in March 2021, we notified all v1 users of the then upcoming sunset in favor of v2 in September 2021 with instructions to migrate. Although we officially deprecated Managed CNAME, some customers were granted exceptions and various zones remained on SSL for SaaS v1. Cloudflare was notified this year through our Bug Bounty program that an external researcher had identified the SSL for SaaS v1 vulnerabilities in the midst of our continued efforts to migrate all customers.
The majority of customers have successfully migrated to the modern v2 setup. For those few that require more time to migrate, we’ve implemented compensating controls to limit the potential scope and reach of this issue for the remaining v1 users. Specifically:
This feature is unavailable for new customer accounts, and new zones within existing customer accounts, to configure via the UI or API
Cloudflare actively maintains an allowlist of zones & customers that currently use the v1 service
We have also implemented WAF custom rules configurations for the remaining customers such that any requests targeting an unauthorized destination will be caught and blocked in their L7 firewall.
The architectural improvement of Cloudflare for SaaS not only closes the gap between certificate and routing validation but also ensures that only verified and authorized domains are routed to their respective origins—effectively eliminating this class of vulnerability.
Next steps
There is no action necessary for Cloudflare customers, with the exception of remaining SSL for SaaS v1 customers, with whom we are actively working to help migrate. While we move to the final phases of sunsetting v1, Cloudflare for SaaS is now the standard across our platform, and all current and future deployments will use this secure, validated model by default.
Conclusion
As always, thank you to the external researchers for responsibly disclosing this vulnerability. We encourage all of our Cloudflare community to submit any identified vulnerabilities to help us continually improve upon the security posture of our products and platform.
We also recognize that the trust you place in us is paramount to the success of your infrastructure on Cloudflare. We consider these vulnerabilities with the utmost concern and will continue to do everything in our power to mitigate impact. Although we are confident in our steps to mitigate impact, we recognize the concern that such incidents may induce. We deeply appreciate your continued trust in our platform and remain committed not only to prioritizing security in all we do, but also acting swiftly and transparently whenever an issue does arise.
Airportr is a service that allows passengers to have their luggage picked up, checked, and delivered to their destinations. As you might expect, it’s used by wealthy or important people. So if the company’s website is insecure, you’d be able to spy on lots of wealthy or important people. And maybe even steal their luggage.
Researchers at the firm CyberX9 found that simple bugs in Airportr’s website allowed them to access virtually all of those users’ personal information, including travel plans, or even gain administrator privileges that would have allowed a hacker to redirect or steal luggage in transit. Among even the small sample of user data that the researchers reviewed and shared with WIRED they found what appear to be the personal information and travel records of multiple government officials and diplomats from the UK, Switzerland, and the US.
“Anyone would have been able to gain or might have gained absolute super-admin access to all the operations and data of this company,” says Himanshu Pathak, CyberX9’s founder and CEO. “The vulnerabilities resulted in complete confidential private information exposure of all airline customers in all countries who used the service of this company, including full control over all the bookings and baggage. Because once you are the super-admin of their most sensitive systems, you have have [sic] the ability to do anything.”
Chinese hackers are exploiting a high-severity vulnerability in Microsoft SharePoint to steal data worldwide:
The vulnerability, tracked as CVE-2025-53770, carries a severity rating of 9.8 out of a possible 10. It gives unauthenticated remote access to SharePoint Servers exposed to the Internet. Starting Friday, researchers began warning of active exploitation of the vulnerability, which affects SharePoint Servers that infrastructure customers run in-house. Microsoft’s cloud-hosted SharePoint Online and Microsoft 365 are not affected.
Here’s Microsoft on patching instructions. Patching isn’t enough, as attackers have used the vulnerability to steal authentication credentials. It’s an absolute mess. CISA has more information. Alsothesefourlinks. Two Slashdotthreads.
This is an unfolding security mess, and quite the hacking coup.
Microsoft is using engineers in China to help maintain the Defense Department’s computer systems—with minimal supervision by U.S. personnel—leaving some of the nation’s most sensitive data vulnerable to hacking from its leading cyber adversary, a ProPublica investigation has found.
The arrangement, which was critical to Microsoft winning the federal government’s cloud computing business a decade ago, relies on U.S. citizens with security clearances to oversee the work and serve as a barrier against espionage and sabotage.
But these workers, known as “digital escorts,” often lack the technical expertise to police foreign engineers with far more advanced skills, ProPublica found. Some are former military personnel with little coding experience who are paid barely more than minimum wage for the work.
This sounds bad, but it’s the way the digital world works. Everything we do is international, deeply international. Making anything US-only is hard, and often infeasible.
EDITED TO ADD: Microsoft has stopped the practice.
The developer of ICEBlock, an iOS app for anonymously reporting sightings of US Immigration and Customs Enforcement (ICE) officials, promises that it “ensures user privacy by storing no personal data.” But that claim has come under scrutiny. ICEBlock creator Joshua Aaron has been accused of making false promises regarding user anonymity and privacy, being “misguided” about the privacy offered by iOS, and of being an Apple fanboy. The issue isn’t what ICEBlock stores. It’s about what it could accidentally reveal through its tight integration with iOS.
Tracked as CVE-2025-5054 and CVE-2025-4598, both vulnerabilities are race condition bugs that could enable a local attacker to obtain access to access sensitive information. Tools like Apport and systemd-coredump are designed to handle crash reporting and core dumps in Linux systems.
[…]
“This means that if a local attacker manages to induce a crash in a privileged process and quickly replaces it with another one with the same process ID that resides inside a mount and pid namespace, apport will attempt to forward the core dump (which might contain sensitive information belonging to the original, privileged process) into the namespace.”
Mitre’s CVE’s program—which provides common naming and other informational resources about cybersecurity vulnerabilities—was about to be cancelled, as the US Department of Homeland Security failed to renew the contact. It was funded for eleven more months at the last minute.
This is a big deal. The CVE program is one of those pieces of common infrastructure that everyone benefits from. Losing it will bring us back to a world where there’s no single way to talk about vulnerabilities. It’s kind of crazy to think that the US government might damage its own security in this way—but I suppose no crazier than any of the other ways the US is working against its own interests right now.
Sasha Romanosky, senior policy researcher at the Rand Corporation, branded the end to the CVE program as “tragic,” a sentiment echoed by many cybersecurity and CVE experts reached for comment.
“CVE naming and assignment to software packages and versions are the foundation upon which the software vulnerability ecosystem is based,” Romanosky said. “Without it, we can’t track newly discovered vulnerabilities. We can’t score their severity or predict their exploitation. And we certainly wouldn’t be able to make the best decisions regarding patching them.”
Ben Edwards, principal research scientist at Bitsight, told CSO, “My reaction is sadness and disappointment. This is a valuable resource that should absolutely be funded, and not renewing the contract is a mistake.”
He added “I am hopeful any interruption is brief and that if the contract fails to be renewed, other stakeholders within the ecosystem can pick up where MITRE left off. The federated framework and openness of the system make this possible, but it’ll be a rocky road if operations do need to shift to another entity.”
More similar quotes in the article.
My guess is that we will somehow figure out how to transition this program to continue without the US government. It’s too important to be at risk.
Microsoft discovered eleven vulnerabilities in GRUB2, including integer and buffer overflows in filesystem parsers, command flaws, and a side-channel in cryptographic comparison.
Additionally, 9 buffer overflows in parsing SquashFS, EXT4, CramFS, JFFS2, and symlinks were discovered in U-Boot and Barebox, which require physical access to exploit.
The newly discovered flaws impact devices relying on UEFI Secure Boot, and if the right conditions are met, attackers can bypass security protections to execute arbitrary code on the device.
Nothing major here. These aren’t exploitable out of the box. But that an AI system can do this at all is impressive, and I expect their capabilities to continue to improve.
US National Security Advisor Mike Waltz, who started the now-infamous group chat coordinating a US attack against the Yemen-based Houthis on March 15, is seemingly now suggesting that the secure messaging service Signal has security vulnerabilities.
"I didn’t see this loser in the group," Waltz told Fox News about Atlantic editor in chief Jeffrey Goldberg, whom Waltz invited to the chat. "Whether he did it deliberately or it happened in some other technical mean, is something we’re trying to figure out."
Waltz’s implication that Goldberg may have hacked his way in was followed by a report from CBS News that the US National Security Agency (NSA) had sent out a bulletin to its employees last month warning them about a security "vulnerability" identified in Signal.
The truth, however, is much more interesting. If Signal has vulnerabilities, then China, Russia, and other US adversaries suddenly have a new incentive to discover them. At the same time, the NSA urgently needs to find and fix any vulnerabilities quickly as it can—and similarly, ensure that commercial smartphones are free of backdoors—access points that allow people other than a smartphone’s user to bypass the usual security authentication methods to access the device’s contents.
That is essential for anyone who wants to keep their communications private, which should be all of us.
It’s common knowledge that the NSA’s mission is breaking into and eavesdropping on other countries’ networks. (During President George W. Bush’s administration, the NSA conducted warrantless taps into domestic communications as well—surveillance that several district courts ruled to be illegal before those decisions were later overturned by appeals courts. To this day, many legal experts maintain that the program violated federal privacy protections.) But the organization has a secondary, complementary responsibility: to protect US communications from others who want to spy on them. That is to say: While one part of the NSA is listening into foreign communications, another part is stopping foreigners from doing the same to Americans.
Those missions never contradicted during the Cold War, when allied and enemy communications were wholly separate. Today, though, everyone uses the same computers, the same software, and the same networks. That creates a tension.
When the NSA discovers a technological vulnerability in a service such as Signal (or buys one on the thriving clandestine vulnerability market), does it exploit it in secret, or reveal it so that it can be fixed? Since at least 2014, a US government interagency "equities" process has been used to decide whether it is in the national interest to take advantage of a particular security flaw, or to fix it. The trade-offs are often complicated and hard.
Waltz—along with Vice President J.D. Vance, Defense Secretary Pete Hegseth, and the other officials in the Signal group—have just made the trade-offs much tougher to resolve. Signal is both widely available and widely used. Smaller governments that can’t afford their own military-grade encryption use it. Journalists, human rights workers, persecuted minorities, dissidents, corporate executives, and criminals around the world use it. Many of these populations are of great interest to the NSA.
At the same time, as we have now discovered, the app is being used for operational US military traffic. So, what does the NSA do if it finds a security flaw in Signal?
Previously, it might have preferred to keep the flaw quiet and use it to listen to adversaries. Now, if the agency does that, it risks someone else finding the same vulnerability and using it against the US government. And if it was later disclosed that the NSA could have fixed the problem and didn’t, then the results might be catastrophic for the agency.
Smartphones present a similar trade-off. The biggest risk of eavesdropping on a Signal conversation comes from the individual phones that the app is running on. While it’s largely unclear whether the US officials involved had downloaded the app onto personal or government-issued phones—although Witkoff suggested on X that the program was on his "personal devices"—smartphones are consumer devices, not at all suitable for classified US government conversations. An entire industry of spyware companies sells capabilities to remotely hack smartphones for any country willing to pay. More capable countries have more sophisticated operations. Just last year, attacks that were later attributed to China attempted to access both President Donald Trump and Vance’s smartphones. Previously, the FBI—as well as law enforcement agencies in other countries—have pressured both Apple and Google to add "backdoors" in their phones to more easily facilitate court-authorized eavesdropping.
These backdoors would create, of course, another vulnerability to be exploited. A separate attack from China last year accessed a similar capability built into US telecommunications networks.
The vulnerabilities equities have swung against weakened smartphone security and toward protecting the devices that senior government officials now use to discuss military secrets. That also means that they have swung against the US government hoarding Signal vulnerabilities—and toward full disclosure.
This is plausibly good news for Americans who want to talk among themselves without having anyone, government or otherwise, listen in. We don’t know what pressure the Trump administration is using to make intelligence services fall into line, but it isn’t crazy to worry that the NSA might again start monitoring domestic communications.
Because of the Signal chat leak, it’s less likely that they’ll use vulnerabilities in Signal to do that. Equally, bad actors such as drug cartels may also feel safer using Signal. Their security against the US government lies in the fact that the US government shares their vulnerabilities. No one wants their secrets exposed.
I have long advocated for a "defense dominant" cybersecurity strategy. As long as smartphones are in the pocket of every government official, police officer, judge, CEO, and nuclear power plant operator—and now that they are being used for what the White House now calls calls "sensitive," if not outright classified conversations among cabinet members—we need them to be as secure as possible. And that means no government-mandated backdoors.
We may find out more about how officials—including the vice president of the United States—came to be using Signal on what seem to be consumer-grade smartphones, in a apparent breach of the laws on government records. It’s unlikely that they really thought through the consequences of their actions.
Nonetheless, those consequences are real. Other governments, possibly including US allies, will now have much more incentive to break Signal’s security than they did in the past, and more incentive to hack US government smartphones than they did before March 24.
For just the same reason, the US government has urgent incentives to protect them.
On January 23, 2025, Cloudflare was notified via its Bug Bounty Program of a vulnerability in Cloudflare’s Mutual TLS (mTLS) implementation.
The vulnerability affected customers who were using mTLS and involved a flaw in our session resumption handling. Cloudflare’s investigation revealed no evidence that the vulnerability was being actively exploited. And tracked asCVE-2025-23419, Cloudflare mitigated the vulnerability within 32 hours after being notified. Customers who were using Cloudflare’s API shield in conjunction with WAF custom rules that validated the issuer’s Subject Key Identifier (SKI) were not vulnerable. Access policies such as identity verification, IP address restrictions, and device posture assessments were also not vulnerable.
Background
The bug bounty report detailed that a client with a valid mTLS certificate for one Cloudflare zone could use the same certificate to resume a TLS session with another Cloudflare zone using mTLS, without having to authenticate the certificate with the second zone.
Cloudflare customers can implement mTLS through Cloudflare API Shield with Custom Firewall Rules and the Cloudflare Zero Trust product suite. Cloudflare establishes the TLS session with the client and forwards the client certificate to Cloudflare’s Firewall or Zero Trust products, where customer policies are enforced.
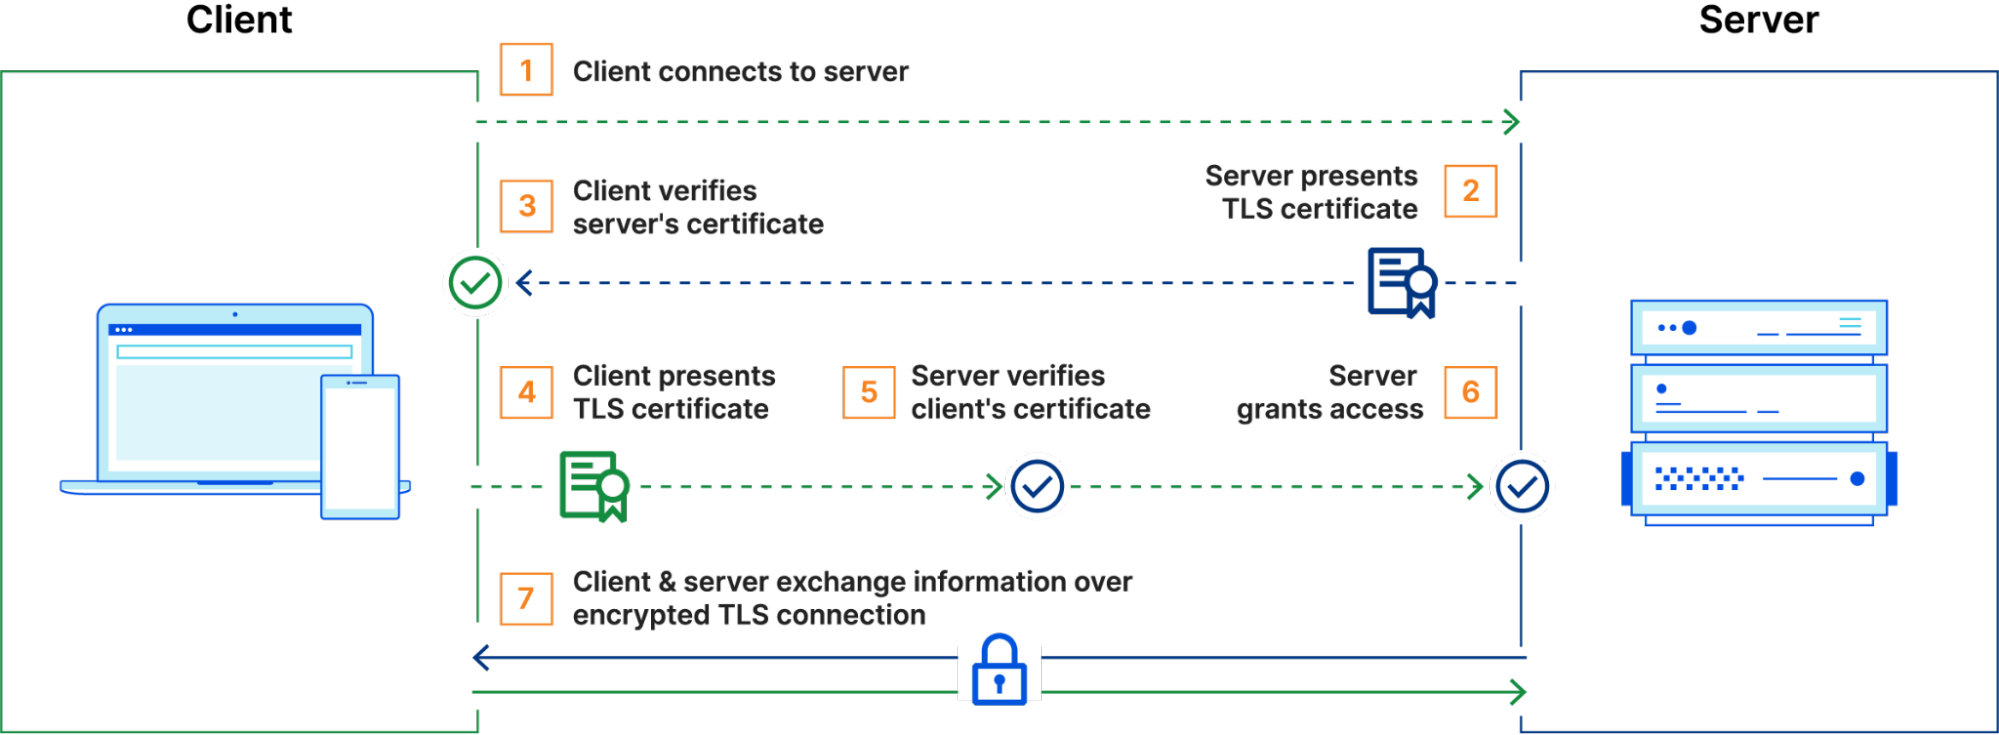
mTLS operates by extending the standard TLS handshake to require authentication from both sides of a connection – the client and the server. In a typical TLS session, a client connects to a server, which presents its TLS certificate. The client verifies the certificate, and upon successful validation, an encrypted session is established. However, with mTLS, the client also presents its own TLS certificate, which the server verifies before the connection is fully established. Only if both certificates are validated does the session proceed, ensuring bidirectional trust.
mTLS is useful for securing API communications, as it ensures that only legitimate and authenticated clients can interact with backend services. Unlike traditional authentication mechanisms that rely on credentials or tokens, mTLS requires possession of a valid certificate and its corresponding private key.
To improve TLS connection performance, Cloudflare employs session resumption. Session resumption speeds up the handshake process, reducing both latency and resource consumption. The core idea is that once a client and server have successfully completed a TLS handshake, future handshakes should be streamlined — assuming that fundamental parameters such as the cipher suite or TLS version remain unchanged.
There are two primary mechanisms for session resumption: session IDs and session tickets. With session IDs, the server stores the session context and associates it with a unique session ID. When a client reconnects and presents this session ID in its ClientHello message, the server checks its cache. If the session is still valid, the handshake is resumed using the cached state.
Session tickets function in a stateless manner. Instead of storing session data, the server encrypts the session context and sends it to the client as a session ticket. In future connections, the client includes this ticket in its ClientHello, which the server can then decrypt to restore the session, eliminating the need for the server to maintain session state.
A resumed mTLS session leverages previously established trust, allowing clients to reconnect to a protected application without needing to re-initiate an mTLS handshake.
The mTLS resumption vulnerability
In Cloudflare’s mTLS implementation, however, session resumption introduced an unintended behavior. BoringSSL, the TLS library that Cloudflare uses, will store the client certificate from the originating, full TLS handshake in the session. Upon resuming that session, the client certificate is not revalidated against the full chain of trust, and the original handshake’s verification status is respected. To avoid this situation, BoringSSL provides an API to partition session caches/tickets between different “contexts” defined by the application. Unfortunately, Cloudflare’s use of this API was not correct, which allowed TLS sessions to be resumed when they shouldn’t have been.
To exploit this vulnerability, the security researcher first set up two zones on Cloudflare and configured them behind Cloudflare’s proxy with mTLS enabled. Once their domains were configured, the researcher authenticated to the first zone using a valid client certificate, allowing Cloudflare to issue a TLS session ticket against that zone.
The researcher then changed the TLS Server Name Indication (SNI) and HTTP Host header from the first zone (which they had authenticated with) to target the second zone (which they had not authenticated with). The researcher then presented the session ticket when handshaking with the second Cloudflare-protected mTLS zone. This resulted in Cloudflare resuming the session with the second zone and reporting verification status for the cached client certificate as successful,bypassing the mTLS authentication that would normally be required to initiate a session.
If you were using additional validation methods in your API Shield or Access policies – for example, checking the issuers SKI, identity verification, IP address restrictions, or device posture assessments – these controls continued to function as intended. However, due to the issue with TLS session resumption, the mTLS checks mistakenly returned a passing result without re-evaluating the full certificate chain.
Remediation and next steps
We have disabled TLS session resumption for all customers that have mTLS enabled. As a result, Cloudflare will no longer allow resuming sessions that cache client certificates and their verification status.
We are exploring ways to bring back the performance improvements from TLS session resumption for mTLS customers.
Further hardening
Customers can further harden their mTLS configuration and add enhanced logging to detect future issues by using Cloudflare’s Transform Rules, logging, and firewall features.
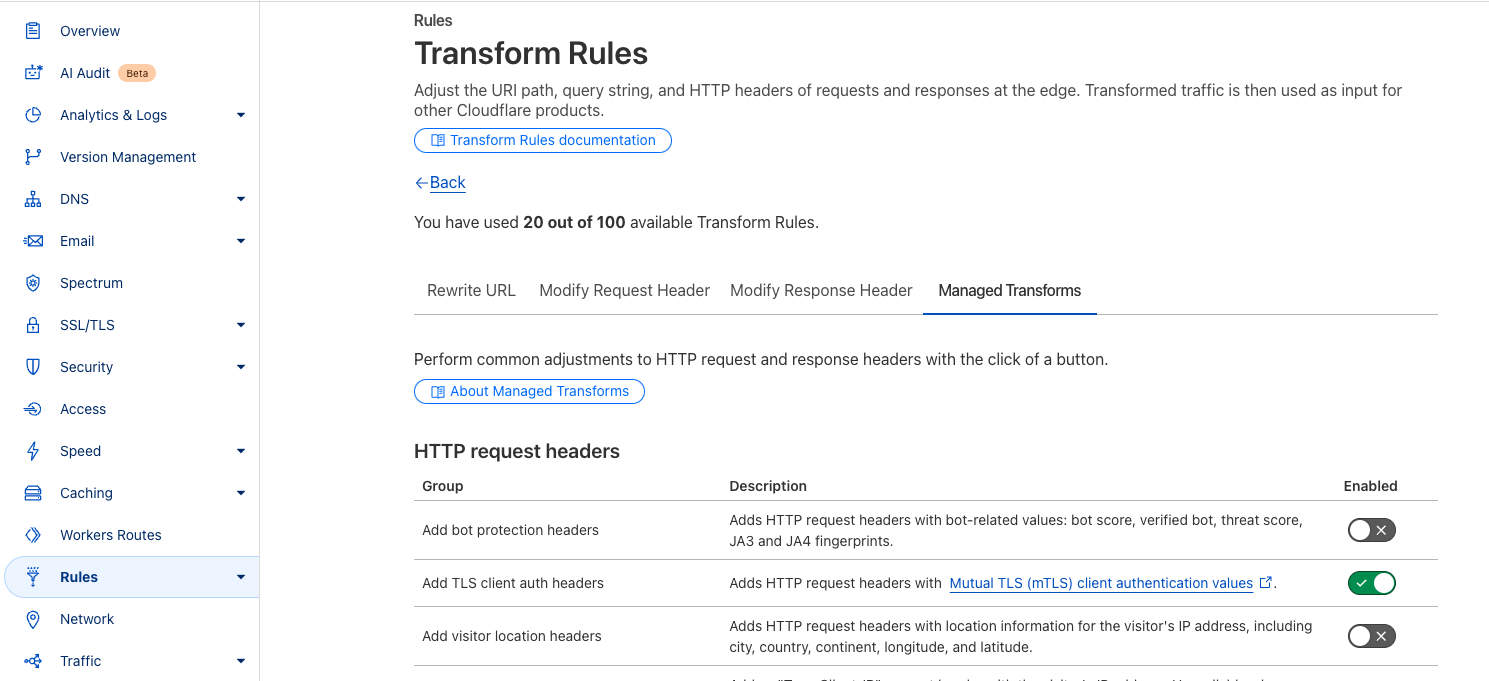
While Cloudflare has mitigated the issue by disabling session resumption for mTLS connections, customers may want to implement additional monitoring at their origin to enforce stricter authentication policies. All customers using mTLS can also enable additional request headers using our Managed Transforms product. Enabling this feature allows us to pass additional metadata to your origin with the details of the client certificate that was used for the connection.
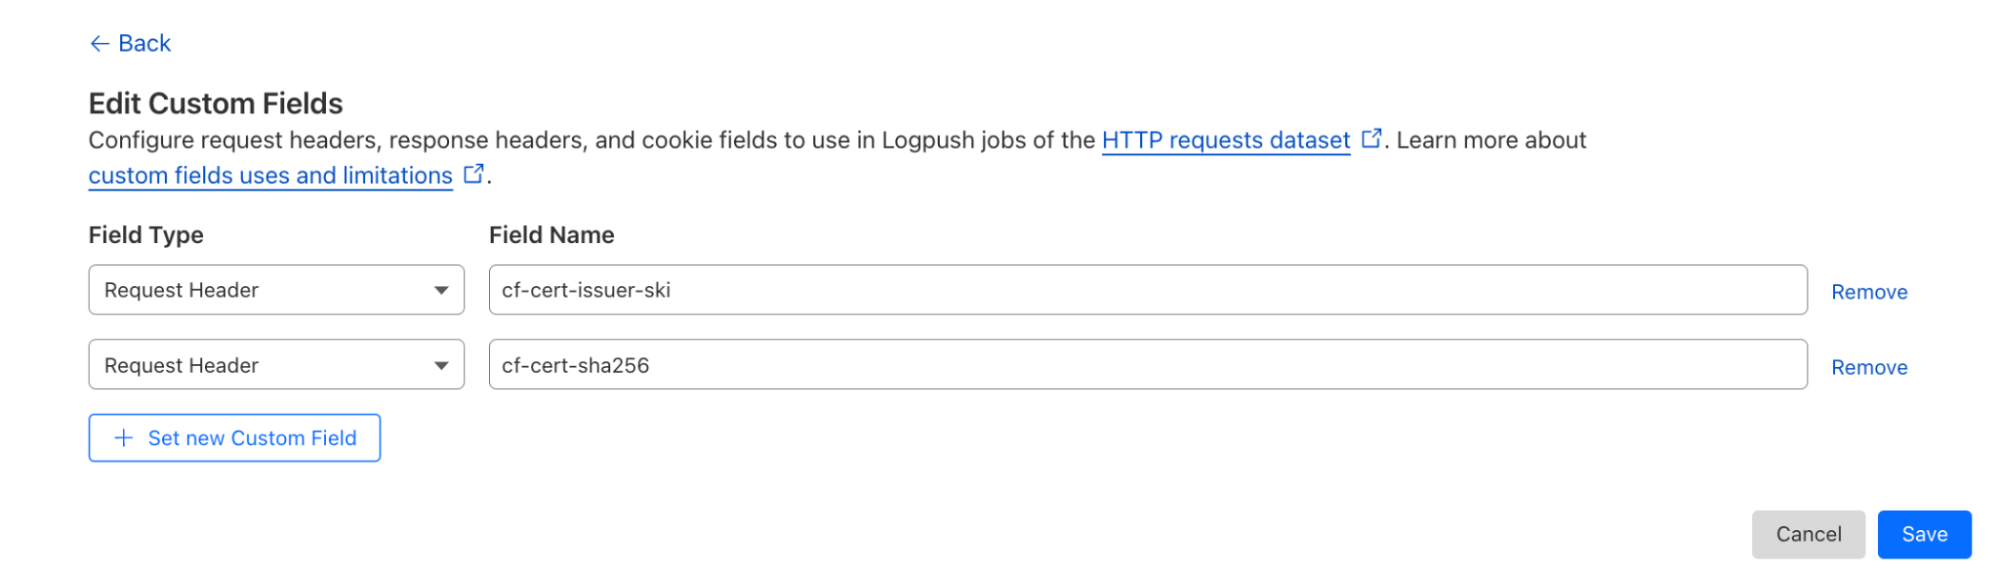
Enabling this feature allows you to see the following headers where mTLS is being utilized on a request.
Customers already logging this information — either at their origin or via Cloudflare Logs — can retroactively check for unexpected certificate hashes or issuers that did not trigger any security policy.
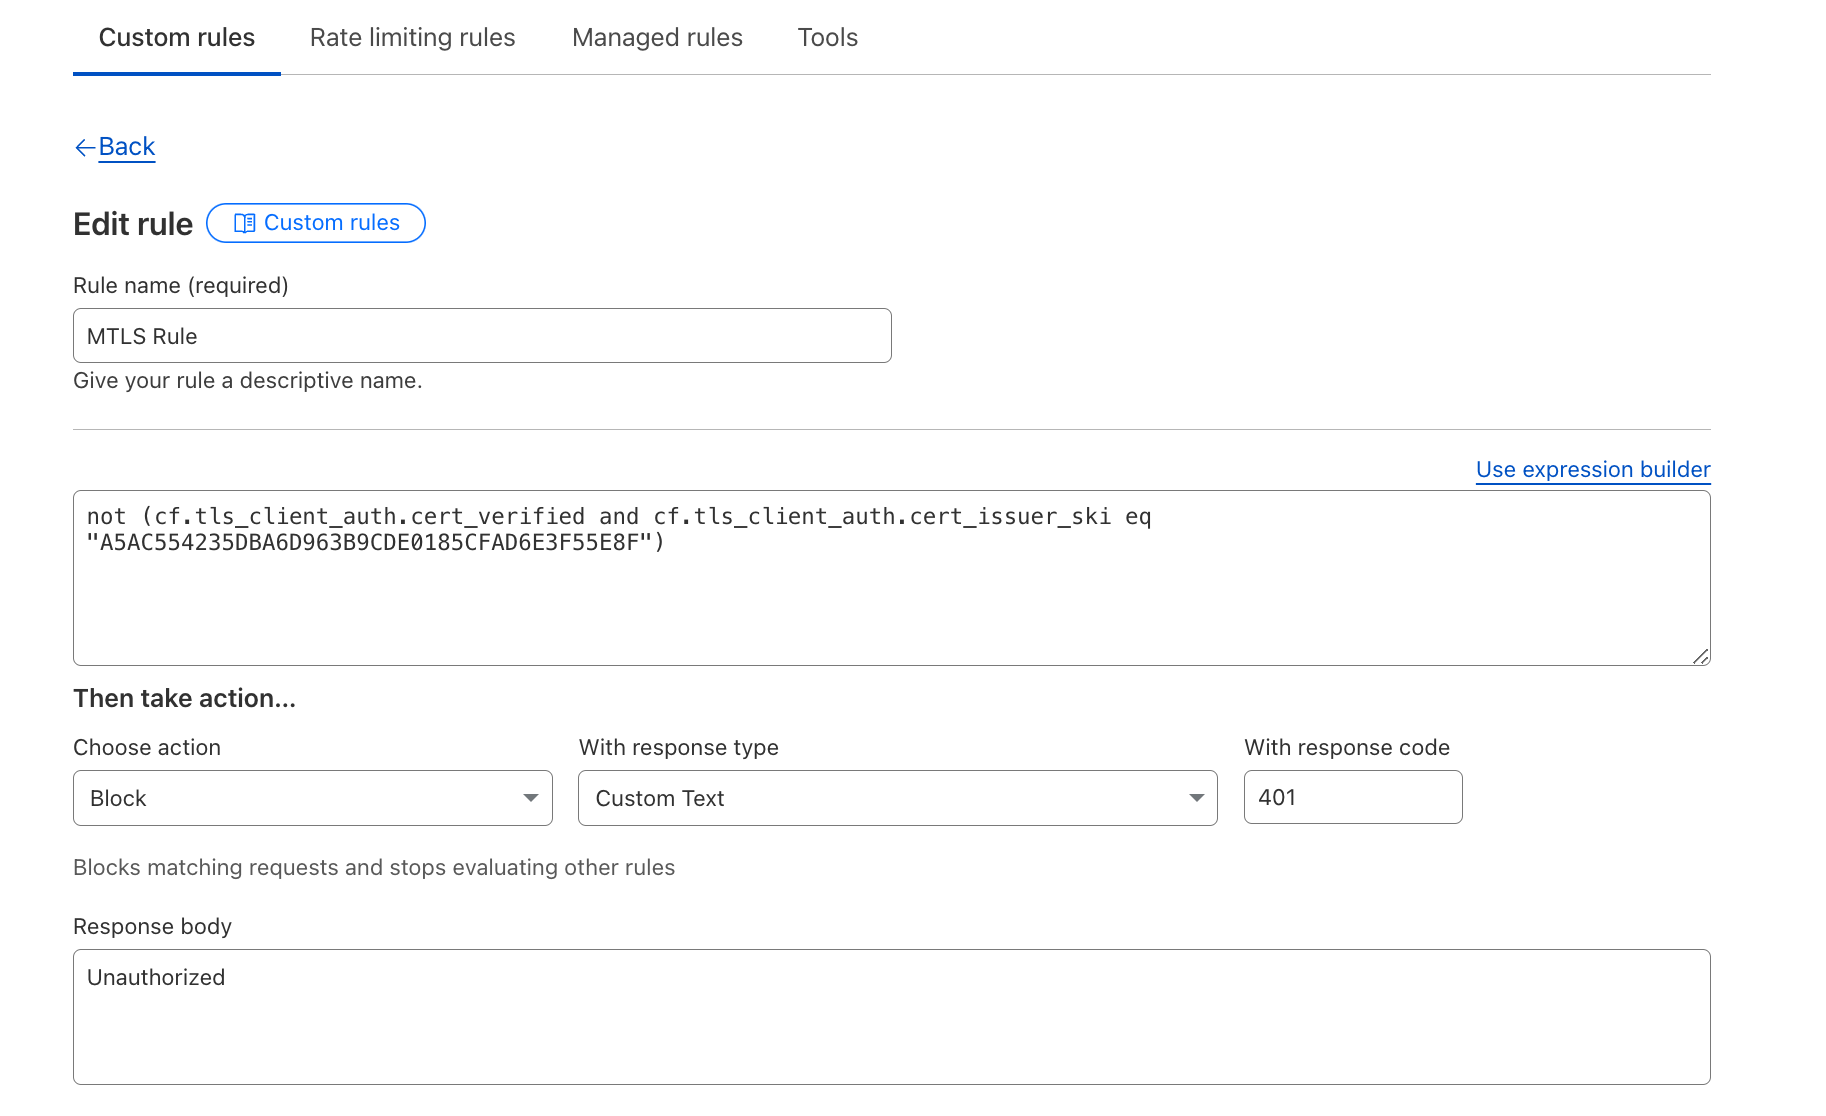
Users are also able to use this information within their WAF custom rules to conduct additional checks. For example, checking the Issuer’s SKI can provide an extra layer of security.
Customers who enabled this additional check were not vulnerable.
Conclusion
We sincerely thank the security researcher who responsibly disclosed this issue via our HackerOne Bug Bounty Program, allowing us to identify and mitigate the vulnerability. We welcome further submissions from our community of researchers to continually improve our products’ security.
Finally, we want to apologize to our mTLS customers. Security is at the core of everything we do at Cloudflare, and we deeply regret any concerns this issue may have caused. We have taken immediate steps to resolve the vulnerability and have implemented additional safeguards to prevent similar issues in the future.
Timeline
All timestamps are in UTC
2025-01-23 15:40 – Cloudflare is notified of a vulnerability in Mutual TLS and the use of session resumption.
2025-01-23 16:02 to 21:06 – Cloudflare validates Mutual TLS vulnerability and prepares a release to disable session resumption for Mutual TLS.
2025-01-23 21:26 – Cloudflare begins rollout of remediation.
2025-01-24 20:15 – Rollout completed. Vulnerability is remediated.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.