Last month, Anthropic made a remarkable announcement about its new model, Claude Mythos Preview: it was so good at finding security vulnerabilities in software that the company would not release it to the general public. Instead, it would only be available to a select group of companies to scan and fix their own software.
The announcement requires context—but it contained an essential truth.
While Anthropic’s model is really good at finding software vulnerabilities, so are other models. The UK’s AI Security Institute found that OpenAI’s GPT-5.5, already generally available, is comparable in capability. The company Aisle reproduced Anthropic’s published results with smaller, cheaper models.
At the same time, Anthropic’s refusal to publicly release its new model makes a virtue out of necessity. Mythos is very expensive to run, and the company doesn’t appear to have the resources for a general release. What better way to juice the company’s valuation than to hint at capabilities but not prove them, and then have othersparrot their claims?
Nonetheless, the truth is scary. Modern generative AI systems—not just Anthropic’s, but OpenAI’s and other, open-source models—are getting really good at finding and exploiting vulnerabilities in software. And that has important ramifications for cybersecurity: on both the offense and the defense.
Attackers will use these capabilities to find, and automatically hack, vulnerabilities in systems of all kinds. They will be able to break into critical systems around the world, sometimes to plant ransomware and make money, sometimes to steal data for espionage purposes, and sometimes to control systems in times of hostility. This will make the world a much more dangerous, and more volatile, place.
But at the same time, defenders will use these same capabilities to find, and then patch, many of those same systems. For example, Mozilla used Mythos to find 271 vulnerabilities in Firefox. Those vulnerabilities have been fixed, and will never again be available to attackers. In the future, AIs automatically finding and fixing vulnerabilities in all software will be a normal part of the development process, which will result in much more secure software.
Of course, it’s not that simple. We should expect a deluge of both attackers using newly found vulnerabilities to break into systems, and at the same time much more frequent software updates for every app and device we use. But lots of systems aren’t patchable, and many systems that are don’t get patched, meaning that many vulnerabilities will stick around. And it does seem that finding and exploiting is easier than finding and fixing. All of this points to a more dangerous short-term future. Organizations will need to adapt their security to this new reality.
But it’s the long term that we need to focus on. Mythos isn’t unique, but it’s more capable than many models that have come before. And it’s less capable than models that will come after. AIs are much better at writing software than they were just six months ago. There’s every reason to believe that they will continue to get better, which means that they will get better at writing more secure software. The endgame gives AI-enhanced defenders advantages over AI-enhanced attackers.
Even more interesting are the broader implications. The same searching, pattern-matching and reasoning capabilities that make these models so good at analyzing software almost certainly apply to similar systems. The tax code isn’t computer code, but it’s a series of algorithms with inputs and outputs. It has vulnerabilities; we call them tax loopholes. It has exploits; we call them tax avoidance strategies. And it has black hat hackers: attorneys and accountants.
Just as these models are finding hundreds of vulnerabilities in complex software systems, we should expect them to be equally effective at finding many new and undiscovered tax loopholes. I am confident that the major investment banks are working on this right now, in secret. They’ve fed AI the tax code of the US, or the UK, or maybe every industrialized country, and tasked the system with looking for money-saving strategies. How many tax loopholes will those AIs find? Ten? One hundred? One thousand? The Double Dutch Irish Sandwich is a tax loophole that involves multiple different tax jurisdictions. Can AIs find loopholes even more complex? We have no idea.
Sure, the AIs will come up with a bunch of tricks that won’t work, but that’s where those attorneys and accountants come in—to verify, and then justify, the loopholes. And then to market them to their wealthy clients.
As goes the tax code, so goes any other complex system of rules and strategies. These models could be tasked with finding loopholes in environmental rules, or food and safety rules—anywhere there are complex regulatory systems and powerful people who want to evade those rules.
The results will be much worse than insecure computers. Tax loopholes result in less revenue collected by governments, and regulatory loopholes allow the powerful to skirt the rules, both of which have all sorts of social ramifications. And while software vendors can patch their systems in days, it generally takes years for a country to amend its tax code. And that process is political, with lobbyists pressuring legislators not to patch. Just look at the carried interest loophole, a US tax dodge that has been exploited for decades. Various administrations have tried to close the vulnerability, but legislators just can’t seem to resist lobbyists long enough to patch it.
AI technologies are poised to remake much of society. Just as the industrial revolution gave humans the ability to consume calories outside of their bodies at scale, the AI revolution will give humans the ability to perform cognitive tasks outside of their bodies at scale. Our systems aren’t designed for that; they’re designed for more human paces of cognition. We’re seeing it right now in the deluge of software vulnerabilities that these models are finding and exploiting. And we will soon see it in a deluge of vulnerabilities in all sorts of other systems of rules. Adapting to this new reality will be hard, but we don’t have any choice.
The UK’s AI Security Institute evaluated GPT-5.5’s ability to find security vulnerabilities, and found that it is comparable to Claude Mythos. Note that the OpenAI model is generally available.
copy.fail is a Linux kernel local privilege escalation, not a browser or clipboard attack. Disclosed by Theori on 29 April 2026 with a working PoC.
It abuses the kernel crypto API (AF_ALG sockets) plus splice() to write four bytes at a time straight into the page cache of a file the attacker does not own.
The exploit works unmodified across Ubuntu, RHEL, Debian, SUSE, Amazon Linux, Fedora and most others. No race condition, no per-distro offsets.
The file on disk is never modified. AIDE, Tripwire and checksum-based monitoring see nothing.
Kubernetes Pod Security Standards (Restricted) and the default RuntimeDefault seccomp profile do not block the syscall used. A custom seccomp profile is needed.
The mainline fix landed on 1 April. Distros are rolling kernels out now. Patch.
“Local privilege escalation” sounds dry, so let me unpack it. It means: an attacker who already has some way to run code on the machine, even as the most boring unprivileged user, can promote themselves to root. From there they can read every file, install backdoors, watch every process, and pivot to other systems.
Why does that matter on shared infrastructure? Because “local” covers a lot of ground in 2026: every container on a shared Kubernetes node, every tenant on a shared hosting box, every CI/CD job that runs untrusted pull-request code, every WSL2 instance on a Windows laptop, every containerised AI agent given shell access. They all share one Linux kernel with their neighbours. A kernel LPE collapses that boundary.
On April 29, 2026, a Linux kernel local privilege escalation vulnerability was publicly disclosed under the name “Copy Fail” (CVE-2026-31431). Cloudflare’s Security and Engineering teams began assessing the vulnerability as soon as it was disclosed. We reviewed the exploit technique, evaluated exposure across our infrastructure, and validated that our existing behavioral detections could identify the exploit pattern within minutes.
There was no impact to the Cloudflare environment, no customer data was at risk, and no services were disrupted at any point. Read on to learn how our preparedness paid off.
Background
Our Linux kernel release process
Cloudflare operates a global Linux server infrastructure at an immense scale, with datacenters located across 330 cities. We maintain a custom Linux kernel build based on the community’s Long-Term Support (LTS) versions to manage updates effectively at this volume. At any given time, we may utilize multiple LTS versions from various series, such as 6.12 or 6.18, which benefit from extended update periods.
The community regularly merges and releases security and stability updates which trigger an automated job to generate a new internal kernel build approximately every week. These builds undergo testing in our staging data centers to ensure stability before a global rollout. Following a successful release, the Edge Reboot Release (ERR) pipeline manages a systematic update and reboot of the edge infrastructure on a four-week cycle. Our control plane infrastructure typically adopts the most recent kernel, with reboots scheduled according to specific workload requirements.
By the time a CVE becomes public knowledge, the necessary fix has typically been integrated into stable Linux LTS releases for several weeks. Our established procedures ensure that we have already deployed these patches.
At the time of the “Copy Fail” disclosure, the majority of our infrastructure was running the 6.12 LTS version, while a subset of machines had begun transitioning to the newer 6.18 LTS release.
About the Copy Fail vulnerability
It helps to understand the vulnerability before getting to the response story. A comprehensive write-up can be found in the original Xint Code disclosure post.
AF_ALG and the kernel crypto API
The Linux kernel’s internal crypto API manages functions like kTLS and IPsec. Userspace programs access this via the AF_ALG socket family, allowing unprivileged processes to request encryption or decryption. The algif_aead module facilitates this for Authenticated Encryption with Associated Data (AEAD) ciphers.
An unprivileged program follows these steps:
Opens an AF_ALG socket and binds to an AEAD template.
Sets a key and accepts a request socket.
Submits input via sendmsg() or splice().
Executes the operation using recvmsg().
The splice() system call is critical here, as it moves data by passing page cache references.
Memory mechanics: page cache and in-place crypto
The page cache is a shared system cache for file contents. Modifying a page belonging to a setuid binary effectively edits that program for all users until the page is evicted.
The crypto API utilizes scatterlists, which are structures linking various memory pages. In 2017, algif_aead was optimized for in-place operations, chaining destination and reference pages together. This design lacked enforcement to prevent algorithms from writing past intended boundaries.
The vulnerability: out-of-bounds write
When the user executes recvmsg(), the authencesn wrapper in the kernel performs a 4-byte write past the legitimate output region:
By using splice(), an attacker can chain a target file’s page cache pages to the scatterlist. The out-of-bounds write then taints the cached file, allowing an attacker to control which file is modified, the offset, and the specific 4 bytes written. This means the attacker can manipulate the following with this exploit:
File: Any readable file.
Offset: Tunable via assoclen and splice parameters.
Value: Controlled via AAD bytes 4-7 in sendmsg()
The exploit, step by step
The default exploit targets /usr/bin/su, a setuid-root binary present on essentially every distribution.
Cache Reference: Open /usr/bin/su as O_RDONLY and read() to populate the page cache. Use splice() on the file descriptor to pass these page cache references into the crypto scatterlist.
Setup: Create an AF_ALG socket, bind() to authencesn(hmac(sha256),cbc(aes)), set a key, and accept a request socket without needing privileges.
Write Construction: For each 4-byte shellcode chunk:
sendmsg() with AAD bytes 4–7 containing the shellcode.
splice() the binary into a pipe then the AF_ALG socket so assoclen + cryptlen targets the desired .text offset.
Trigger:recvmsg() initiates decryption. authencesn writes its scratch data to the target offset of /usr/bin/su in the page cache. Although the function returns -EBADMSG, the 4-byte write is now in the global page cache.
Execution: Running execve("/usr/bin/su") loads the tainted page cache. Since the binary is setuid-root, the injected shellcode executes with root privileges.
The upstream fix (commit a664bf3d603d) reverts the 2017 in-place optimization, removing the exploit.
How we responded
When the vulnerability was disclosed, many workstreams started in parallel:
Mapping the blast radius: Our security team worked with kernel engineers to determine which kernel versions were vulnerable and assess the potential exposure.
Validating coverage: Security reviewed the exploit technique and confirmed that our existing behavioral detections could identify the exploit pattern during authorized internal validation.
Proactive threat hunting: Security began searching for signs that the vulnerability had been exploited before it was publicly known, going back 48 hours in our fleet-wide logs.
Engineering a mitigation: Kernel engineers began building a runtime mitigation that would protect the fleet without breaking production services.
Continuing software updates: Our engineering teams worked on delivering an updated Linux kernel, which required carefully rebooting and rolling it out across our servers.
There was no customer impact at any point during this response.
Validating detection coverage
One of the first things our security team did was confirm that our existing endpoint detection would catch this exploit. Our servers run behavioral detection that continuously monitors process execution patterns. It doesn’t rely on knowing about specific vulnerabilities; it watches for anomalous behavior across the fleet.
When our engineers validated the vulnerability internally as part of the response, the detection platform flagged it within minutes. The system linked the entire execution chain—starting at the script interpreter, moving through the kernel’s cryptographic subsystem, and ending at the privilege escalation binary—flagging it as malicious based on fleet-wide behavioral patterns.
This happened without a signature update, without a rule change, and without human intervention. Our behavioral detection coverage existed before we wrote any custom logic for this particular Copy File exploit.
The confirmation was important because it meant we had coverage before writing a vulnerability-specific rule.
Hunting for exploitation
While our engineering team moved to a more targeted mitigation, our security investigation had been running since disclosure. This is our standard procedure for any critical vulnerability.
Our security team operates on a simple principle for critical vulnerabilities: assume compromise until you can prove otherwise. The investigation started from the assumption that exploitation could have occurred before the vulnerability was public, and we worked systematically to either confirm or rule it out.
The exploit leaves a distinctive trace in kernel logs when it runs. We searched for that trace across our centralized logging infrastructure, covering 48 hours before the vulnerability was publicly disclosed. If someone had exploited this before the world knew about it, we would have seen it.
We pulled access logs for affected systems and reconstructed who connected, when, and what commands they ran. This gave us a complete forensic picture of interactive activity on potentially affected infrastructure.
We checked that system binaries had not been tampered with, validated cryptographic hashes against known-good package manifests, looked for persistence mechanisms, and audited network connections for anything unusual. Everything was clean.
Incident timeline and impact
Time (UTC)
Event
2026-04-29 16:00
Copy Fail publicly disclosed.
2026-04-29 ~21:00
Security and Engineering teams began assessing fleet exposure and mitigation options before full declaration of the Incident Response process
2026-04-29 22:52
Security confirmed existing behavioral detection covered the Copy Fail exploit pattern. During authorized internal validation, detection flagged the activity within minutes.
2026-04-29 23:01
Existing behavioral detection generated a high-severity alert for exploit-like activity, confirming detection coverage for the technique.
2026-04-29 (evening)
First mitigation attempt pushed to our staging datacenter. The deployment process surfaced a dependency conflict; the mitigation was rolled back. No production systems were affected.
2026-04-29 (overnight)
Engineering drafted bpf-lsm mitigation program.
2026-04-30 03:14
Security incident declared to drive cross-functional collaboration and urgency. Security performed fleetwide threat hunting of historical data to confirm that no malicious activity was present on Cloudflare systems.
2026-04-30 (morning)
Engineering tested the bpf-lsm mitigation program and made it production-ready.
2026-04-30 14:25
Engineering incident declared to coordinate mitigation program and Linux patch rollout.
2026-04-30 ~17:00
Decision made: ship a patched build of the previous LTS line through reboot automation; do not accelerate the new LTS; lean on bpf-lsm in the meantime.
2026-04-30 (afternoon)
Visibility pipeline (eBPF tracing of AF_ALG socket usage) deployed fleet-wide. Gives a complete picture of all legitimate AF_ALG users.
2026-04-30 (evening)
bpf-lsm mitigation program rolled out behind a separate gate to fully mitigate the fleet. End-to-end verification on a previously-vulnerable test node confirms the exploit no longer works.
2026-05-04 (morning)
Reboot automation resumed at normal pace with the patched kernel.
2026-05-04 onward
Servers that had already passed through reboot automation earlier in the week manually rebooted to pick up the patched kernel. Unpatched servers update per our normal reboot automation.
This graph shows the progress of our mitigation program as it progressed through our infrastructure.
How did we mitigate it?
Because of the long timeframe involved in deploying a patched Linux kernel, we also pursued mitigating this exploit without a reboot.
Removing the module
The bug was in the algif_aead kernel module. Therefore, the simple fix was to just remove this module and disallow it from being reloaded.
This mitigation was therefore exactly what the Copy Fail write-up from the security researchers who identified it recommends.
Unfortunately removing the module would have impacted software that leverages the kernel crypto API. This meant that we had to figure out a more surgical mitigation.
Bpf-lsm
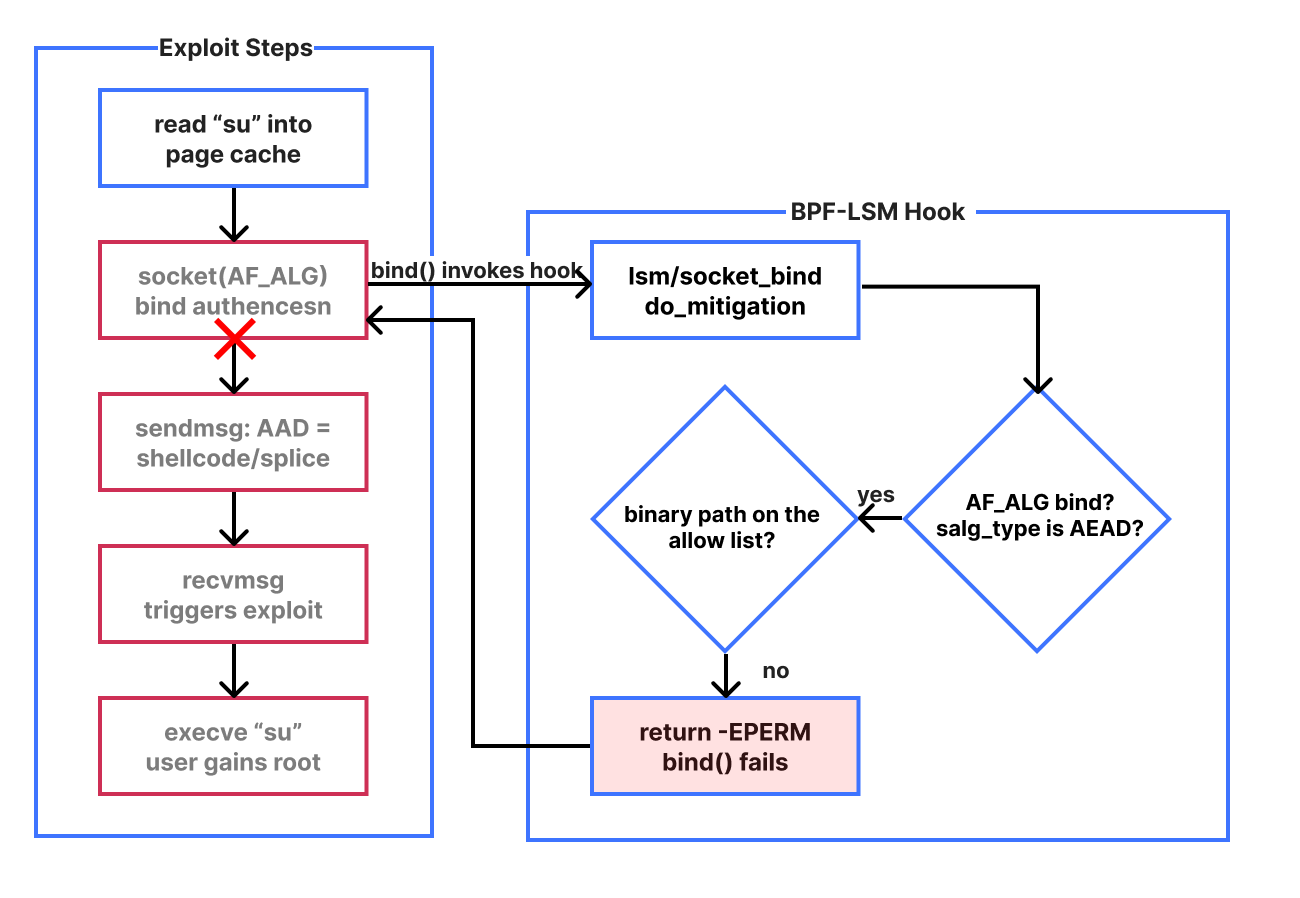
We’ve already developed and deployed such a tool for this exact scenario: bpf-lsm. Instead of removing the module, this tool leaves it loaded for legitimate users and uses a BPF Linux Security Module program to deny the socket_bind LSM hook for everyone else. This completely blocks the front door for any exploits.
A draft of the eBPF program was put together overnight. Team members picked it up the following morning, ran validations, and made it production-ready. The program is fairly straightforward. On every socket_bind call:
If the socket family is not AF_ALG, allow the call through unchanged.
If the family is AF_ALG, check the calling binary’s path against an allow-list of the binaries we know to be legitimate users.
If the binary is on the allow-list, allow the bind. Otherwise, deny it.
To verify the mitigation on a given machine without exploiting it, the Copy Fail write-up gives a one-liner:
python3 -c 'import socket; s = socket.socket(socket.AF_ALG, socket.SOCK_SEQPACKET, 0); s.bind(("aead","authencesn(hmac(sha256),cbc(aes))"));'
On a mitigated machine you get PermissionError: [Errno 1] Operation not permitted (or FileNotFoundError, depending on which mitigation is active) instead of a successful bind.
Rolling it out
Before enabling enforcement, we verified that our known internal service was the sole legitimate AF_ALG user to avoid accidental outages. We used prometheus-ebpf-exporter to hook the socket() syscall and track AF_ALG usage per binary across the fleet. This required no kernel changes and provided aggregate data from hundreds of thousands of servers within hours. Results confirmed the identified service was indeed the only legitimate user.
So the bpf-lsm rollout was deliberately staged in two steps:
Get visibility first. Push the ebpf-exporter config gated by salt. Confirm at the metric layer that the known service is effectively the only thing creating AF_ALG sockets.
Then enforce. Push the bpf-lsm program behind a separate enforcement gate.
In parallel, the upstream backport for our majority LTS line finally became available, and our internal automation built a patched kernel against it.
We started to test the patched kernel in our staging datacenters as soon as possible, then we resumed the longer reboot process in order to fully patch our fleet.
Remediation and follow-up steps
While we were prepared for this scenario, at Cloudflare we’re always learning and improving. Key areas we identified for improvement:
Better visibility into kernel-API dependencies. We will review kernel-subsystem usage across production services, so we can continue to quickly mitigate exploits without service disruption.
Better runtime mitigation. bpf-lsm is a valuable tool for mitigations, but we want to make this tool even better. This will include looking into faster deployments, better playbooks, and better logging and visibility of the tool.
Reduce attack surface of Linux Kernel. Review and audit our kernel configuration. Proactively identify unused modules or features so that we can remove them from our build entirely.
Conclusion
The “Copy Fail” vulnerability presented a unique challenge for us. Despite our practice of deploying Linux patch updates every two weeks, we remained vulnerable because a month-old mainline fix had yet to be backported to our primary kernel line. Despite that, we were still able to roll out patched kernels within hours of the backport’s release. In the interim, bpf-lsm provided a surgical, no-reboot mitigation that secured our fleet. While our initial attempt to disable the problematic module failed, it did so safely within our internal staging environment rather than production, allowing us to identify this dependency.
By the end of the rollout, every machine in our fleet was protected by either a patched kernel or a bpf-lsm program denying the vulnerable code path to non-allow-listed binaries. There was no customer impact at any point during this incident, and we have committed to the follow-up work above to make our response faster and our visibility better the next time something like this lands. Responsible disclosure works, in-kernel visibility tooling pays off in moments exactly like this one, and bpf-lsm continues to be one of the most useful primitives we have for runtime kernel mitigation.
At Cloudflare, critical vulnerability response is a coordinated effort across Security, Engineering, Product, and many other teams. Special thanks to Ali Adnan, Ivan Babrou, Frederik Baetens, Curtis Bray, Piers Cornwell, Everton Didone Foscarini, Rob Dinh, Elle Dougherty, Kevin Flansburg, Matt Fleming, Kimberley Hall, Brandon Harris, Jerry Ho, Oxana Kharitonova, Marek Kroemeke, Fred Lawler, James Munson, Nafeez Nazer, Walead Parviz, Miguel Pato, Evan Pratten, Josh Seba, June Slater, Ryan Timken, Michael Wolf, Jianxin Zeng and everyone else who contributed to the investigation, mitigation, and remediation of Copy Fail. We’d also like to thank the Linux upstream maintainers and Copy Fail researchers whose work helped make a rapid response possible.
DarkSword is a sophisticated piece of malware—probably government designed—that targets iOS.
Google Threat Intelligence Group (GTIG) has identified a new iOS full-chain exploit that leveraged multiple zero-day vulnerabilities to fully compromise devices. Based on toolmarks in recovered payloads, we believe the exploit chain to be called DarkSword. Since at least November 2025, GTIG has observed multiple commercial surveillance vendors and suspected state-sponsored actors utilizing DarkSword in distinct campaigns. These threat actors have deployed the exploit chain against targets in Saudi Arabia, Turkey, Malaysia, and Ukraine.
DarkSword supports iOS versions 18.4 through 18.7 and utilizes six different vulnerabilities to deploy final-stage payloads. GTIG has identified three distinct malware families deployed following a successful DarkSword compromise: GHOSTBLADE, GHOSTKNIFE, and GHOSTSABER. The proliferation of this single exploit chain across disparate threat actors mirrors the previously discovered Coruna iOS exploit kit. Notably, UNC6353, a suspected Russian espionage group previously observed using Coruna, has recently incorporated DarkSword into their watering hole campaigns.
A week after it was identified, a version of it leaked onto the internet, where it is being used more broadly.
This news is a month old. Your devices are safe, assuming you patch regularly.
Two weeks ago, Anthropic announced that its new model, Claude Mythos Preview, can autonomously find and weaponize software vulnerabilities, turning them into working exploits without expert guidance. These were vulnerabilities in key software like operating systems and internet infrastructure that thousands of software developers working on those systems failed to find. This capability will have major security implications, compromising the devices and services we use every day. As a result, Anthropic is not releasing the model to the general public, but instead to a limited number of companies.
The news rocked the internet security community. There were few details in Anthropic’s announcement, angering many observers. Some speculate that Anthropic doesn’t have the GPUs to run the thing, and that cybersecurity was the excuse to limit its release. Others argue Anthropic is holding to its AI safety mission. There’shype and counterhype, reality and marketing. It’s a lot to sort out, even if you’re an expert.
We see Mythos as a real but incremental step, one in a long line of incremental steps. But even incremental steps can be important when we look at the big picture.
How AI Is Changing Cybersecurity
We’ve written about shifting baseline syndrome, a phenomenon that leads people—the public and experts alike—to discount massive long-term changes that are hidden in incremental steps. It has happened with online privacy, and it’s happening with AI. Even if the vulnerabilities found by Mythos could have been found using AI models from last month or last year, they couldn’t have been found by AI models from five years ago.
The Mythos announcement reminds us that AI has come a long way in just a few years: The baseline really has shifted. Finding vulnerabilities in source code is the type of task that today’s large language models excel at. Regardless of whether it happened last year or will happen next year, it’s been clear for a while this kind of capability was coming soon. The question is how we adapt to it.
We don’t believe that an AI that can hack autonomously will create permanent asymmetry between offense and defense; it’s likely to be more nuanced than that. Some vulnerabilities can be found, verified, and patched automatically. Some vulnerabilities will be hard to find but easy to verify and patch—consider generic cloud-hosted web applications built on standard software stacks, where updates can be deployed quickly. Still others will be easy to find (even without powerful AI) and relatively easy to verify, but harder or impossible to patch, such as IoT appliances and industrial equipment that are rarely updated or can’t be easily modified.
Then there are systems whose vulnerabilities will be easy to find in code but difficult to verify in practice. For example, complex distributed systems and cloud platforms can be composed of thousands of interacting services running in parallel, making it difficult to distinguish real vulnerabilities from false positives and to reliably reproduce them.
So we must separate the patchable from the unpatchable, and the easy to verify from the hard to verify. This taxonomy also provides us guidance for how to protect such systems in an era of powerful AI vulnerability-finding tools.
Unpatchable or hard to verify systems should be protected by wrapping them in more restrictive, tightly controlled layers. You want your fridge or thermostat or industrial control system behind a restrictive and constantly updated firewall, not freely talking to the internet.
Distributed systems that are fundamentally interconnected should be traceable and should follow the principle of least privilege, where each component has only the access it needs. These are bog-standard security ideas that we might have been tempted to throw out in the era of AI, but they’re still as relevant as ever.
Rethinking Software Security Practices
This also raises the salience of best practices in software engineering. Automated, thorough, and continuous testing was always important. Now we can take this practice a step further and use defensive AI agents to test exploits against a real stack, over and over, until the false positives have been weeded out and the real vulnerabilities and fixes are confirmed. This kind of VulnOps is likely to become a standard part of the development process.
Documentation becomes more valuable, as it can guide an AI agent on a bug-finding mission just as it does developers. And following standard practices and using standard tools and libraries allows AI and engineers alike to recognize patterns more effectively, even in a world of individual and ephemeral instant software—code that can be generated and deployed on demand.
Will this favor offense or defense? The defense eventually, probably, especially in systems that are easy to patch and verify. Fortunately, that includes our phones, web browsers, and major internet services. But today’s cars, electrical transformers, fridges, and lampposts are connected to the internet. Legacy banking and airline systems are networked.
Not all of those are going to get patched as fast as needed, and we may see a few years of constant hacks until we arrive at a new normal: where verification is paramount and software is patched continuously.
This essay was written with Barath Raghavan, and originally appeared in IEEE Spectrum.
Last week, Anthropic pulled back the curtain on Claude Mythos Preview, an AI model so capable at finding and exploiting software vulnerabilities that the company decided it was too dangerous to release to the public. Instead, access has been restricted to roughly 50 organizations—Microsoft, Apple, Amazon Web Services, CrowdStrike and other vendors of critical infrastructure—under an initiative called Project Glasswing.
The announcement was accompanied by a barrage of hair-raising anecdotes: thousands of vulnerabilities uncovered across every major operating system and browser, including a 27-year-old bug in OpenBSD, a 16-year-old flaw in FFmpeg. Mythos was able to weaponize a set of vulnerabilities it found in the Firefox browser into 181 usable attacks; Anthropic’s previous flagship model could only achieve two.
This is, in many respects, exactly the kind of responsible disclosure that security researchers have long urged. And yet the public has been given remarkably little with which to evaluate Anthropic’s decision. We have been shown a highlight reel of spectacular successes. However, we can’t tell if we have a blockbuster until they let us see the whole movie.
For example, we don’t know how many times Mythos mistakenly flagged code as vulnerable. Anthropic said security contractors agreed with the AI’s severity rating 198 times, with an 89 per cent severity agreement. That’s impressive, but incomplete. Independent researchers examining similar models have found that AI that detects nearly every real bug also hallucinates plausible-sounding vulnerabilities in patched, correct code.
This matters. A model that autonomously finds and exploits hundreds of vulnerabilities with inhuman precision is a game changer, but a model that generates thousands of false alarms and non-working attacks still needs skilled and knowledgeable humans. Without knowing the rate of false alarms in Mythos’s unfiltered output, we cannot tell whether the examples showcased are representative.
There is a second, subtler problem. Large language models, including Mythos, perform best on inputs that resemble what they were trained on: widely used open-source projects, major browsers, the Linux kernel and popular web frameworks. Concentrating early access among the largest vendors of precisely this software is sensible; it lets them patch first, before adversaries catch up.
But the inverse is also true. Software outside the training distribution—industrial control systems, medical device firmware, bespoke financial infrastructure, regional banking software, older embedded systems—is exactly where out-of-the-box Mythos is likely least able to find or exploit bugs.
However, a sufficiently motivated attacker with domain expertise in one of these fields could nevertheless wield Mythos’s advanced reasoning capabilities as a force multiplier, probing systems that Anthropic’s own engineers lack the specialized knowledge to audit. The danger is not that Mythos fails in those domains; it is that Mythos may succeed for whoever brings the expertise.
Broader, structured access for academic researchers and domain specialists—cardiologists’ partners in medical device security, control-systems engineers, researchers in less prominent languages and ecosystems—would meaningfully reduce this asymmetry. Fifty companies, however well chosen, cannot substitute for the distributed expertise of the entire research community.
None of this is an indictment of Anthropic. By all appearances the company is trying to act responsibly, and its decision to hold the model back is evidence of seriousness.
But Anthropic is a private company and, in some ways, still a start-up. Yet it is making unilateral decisions about which pieces of our critical global infrastructure get defended first, and which must wait their turn.
It has finite staff, finite budget and finite expertise. It will miss things, and when the thing missed is in the software running a hospital or a power grid, the cost will be borne by people who never had a say.
The security problem is far greater than one company and one model. There’s no reason to believe that Mythos Preview is unique. (Not to be outdone, OpenAI announced that its new GPT-5.3-Codex is so dangerous that the model also will not be released to the general public.) And it’s unclear how much of an advance these new models represent. The security company Aisle was able to replicate many of Anthropic’s published anecdotes using smaller, cheaper, public AI models.
Any decisions we make about whether and how to release these powerful models are more than one company’s responsibility. Ultimately, this will probably lead to regulation. That will be hard to get right and requires a long process of consultation and feedback.
In the short term, we need something simpler: greater transparency and information sharing with the broader community. This doesn’t necessarily mean making powerful models like Claude Mythos widely available. Rather, it means sharing as much data and information as possible, so that we can collectively make informed decisions.
We need globally co-ordinated frameworks for independent auditing, mandatory disclosure of aggregate performance metrics and funded access for academic and civil-society researchers.
This has implications for national security, personal safety and corporate competitiveness. Any technology that can find thousands of exploitable flaws in the systems we all depend on should not be governed solely by the internal judgment of its creators, however well intentioned.
Until that changes, each Mythos-class release will put the world at the edge of another precipice, without any visibility into whether there is a landing out of view just below, or whether this time the drop will be fatal. That is not a choice a for-profit corporation should be allowed to make in a democratic society. Nor should such a company be able to restrict the ability of society to make choices about its own security.
This essay was written with David Lie, and originally appeared in The Globe and Mail.
The cybersecurity industry is obsessing over Anthropic’s new model, Claude Mythos Preview, and its effects on cybersecurity. Anthropic said that it is not releasing it to the general public because of its cyberattack capabilities, and has launched Project Glasswing to run the model against a whole slew of public domain and proprietary software, with the aim of finding and patching all the vulnerabilities before hackers get their hands on the model and exploit them.
There’s a lot here, and I hope to write something more considered in the coming week, but I want to make some quick observations.
One: This is very much a PR play by Anthropic—and it worked. Lots of reporters are breathlesslyrepeating Anthropic’s talkingpoints, without engaging with them critically. OpenAI, presumably pissed that Anthropic’s new model has gotten so much positive press and wanting to grab some of the spotlight for itself, announced its model is just as scary, and won’t be released to the general public, either.
Two: These models do demonstrate an increased sophistication in their cyberattack capabilities. They write effective exploits—taking the vulnerabilities they find and operationalizing them—without human involvement. They can find more complex vulnerabilities: chaining together several memory corruption bugs, for example. And they can do more with one-shot prompting, without requiring orchestration and agent configuration infrastructure.
Three: Anthropic might have a good PR team, but the problem isn’t with Mythos Preview. The security company Aisle was able to replicate the vulnerabilities that Anthropic found, using older, cheaper, public models. But there is a difference between finding a vulnerability and turning it into an attack. This points to a current advantage to the defender. Finding for the purposes of fixing is easier for an AI than finding plus exploiting. This advantage is likely to shrink, as ever more powerful models become available to the general public.
Four: Everyone who is panicking about the ramifications of this is correct about the problem, even if we can’t predict the exact timeline. Maybe the sea change just happened, with the new models from Anthropic and OpenAI. Maybe it happened six months ago. Maybe it’ll happen in six months. It will happen—I have no doubt about it—and sooner than we are ready for. We can’t predict how much more these models will improve in general, but software seems to be a specialized language that is optimal for AIs.
A couple of weeks ago, I wrote about security in what I called “the age of instant software,” where AIs are superhumanly good at finding, exploiting, and patching vulnerabilities. I stand by everything I wrote there. The urgency is now greater than ever.
I was also part of a large team that wrote a “what to do now” report. The guidance is largely correct: We need to prepare for a world where zero-day exploits are dime-a-dozen, and lots of attackers suddenly have offensive capabilities that far outstrip their skills.
AI is rapidly changing how software is written, deployed, and used. Trends point to a future where AIs can write custom software quickly and easily: “instant software.” Taken to an extreme, it might become easier for a user to have an AI write an application on demand—a spreadsheet, for example—and delete it when you’re done using it than to buy one commercially. Future systems could include a mix: both traditional long-term software and ephemeral instant software that is constantly being written, deployed, modified, and deleted.
AI is changing cybersecurity as well. In particular, AI systems are getting better at finding and patching vulnerabilities in code. This has implications for both attackers and defenders, depending on the ways this and related technologies improve.
In this essay, I want to take an optimistic view of AI’s progress, and to speculate what AI-dominated cybersecurity in an age of instant software might look like. There are a number of unknowns that will factor into how the arms race between attacker and defender might play out.
How flaw discovery might work
On the attacker side, the ability of AIs to automatically find and exploit vulnerabilities has increased dramatically over the past few months. We are already seeing both government and criminal hackers using AI to attack systems. The exploitation part is critical here, because it gives an unsophisticated attacker capabilities far beyond their understanding. As AIs get better, expect more attackers to automate their attacks using AI. And as individuals and organizations can increasingly run powerful AI models locally, AI companies monitoring and disrupting malicious AI use will become increasingly irrelevant.
Expect open-source software, including open-source libraries incorporated in proprietary software, to be the most targeted, because vulnerabilities are easier to find in source code. Unknown No. 1 is how well AI vulnerability discovery tools will work against closed-source commercial software packages. I believe they will soon be good enough to find vulnerabilities just by analyzing a copy of a shipped product, without access to the source code. If that’s true, commercial software will be vulnerable as well.
Particularly vulnerable will be software in IoT devices: things like internet-connected cars, refrigerators, and security cameras. Also industrial IoT software in our internet-connected power grid, oil refineries and pipelines, chemical plants, and so on. IoT software tends to be of much lower quality, and industrial IoT software tends to be legacy.
Instant software is differently vulnerable. It’s not mass market. It’s created for a particular person, organization, or network. The attacker generally won’t have access to any code to analyze, which makes it less likely to be exploited by external attackers. If it’s ephemeral, any vulnerabilities will have a short lifetime. But lots of instant software will live on networks for a long time. And if it gets uploaded to shared tool libraries, attackers will be able to download and analyze that code.
All of this points to a future where AIs will become powerful tools of cyberattack, able to automatically find and exploit vulnerabilities in systems worldwide.
Automating patch creation
But that’s just half of the arms race. Defenders get to use AI, too. These same AI vulnerability-finding technologies are even more valuable for defense. When the defensive side finds an exploitable vulnerability, it can patch the code and deny it to attackers forever.
How this works in practice depends on another related capability: the ability of AIs to patch vulnerable software, which is closely related to their ability to write secure code in the first place.
AIs are not very good at this today; the instant software that AIs create is generally filled with vulnerabilities, both because AIs write insecure code and because the people vibe coding don’t understand security. OpenClaw is a good example of this.
Unknown No. 2 is how much better AIs will get at writing secure code. The fact that they’re trained on massive corpuses of poorly written and insecure code is a handicap, but they are getting better. If they can reliably write vulnerability-free code, it would be an enormous advantage for the defender. And AI-based vulnerability-finding makes it easier for an AI to train on writing secure code.
We can envision a future where AI tools that find and patch vulnerabilities are part of the typical software development process. We can’t say that the code would be vulnerability-free—that’s an impossible goal—but it could be without any easily findable vulnerabilities. If the technology got really good, the code could become essentially vulnerability-free.
Patching lags and legacy software
For new software—both commercial and instant—this future favors the defender. For commercial and conventional open-source software, it’s not that simple. Right now, the world is filled with legacy software. Much of it—like IoT device software—has no dedicated security team to update it. Sometimes it is incapable of being patched. Just as it’s harder for AIs to find vulnerabilities when they don’t have access to the source code, it’s harder for AIs to patch software when they are not embedded in the development process.
I’m not as confident that AI systems will be able to patch vulnerabilities as easily as they can find them, because patching often requires more holistic testing and understanding. That’s Unknown No. 3: how quickly AIs will be able to create reliable software updates for the vulnerabilities they find, and how quickly customers can update their systems.
Today, there is a time lag between when a vendor issues a patch and customers install that update. That time lag is even longer for large organizational software; the risk of an update breaking the underlying software system is just too great for organizations to roll out updates without testing them first. But if AI can help speed up that process, by writing patches faster and more reliably, and by testing them in some AI-generated twin environment, the advantage goes to the defender. If not, the attacker will still have a window to attack systems until a vulnerability is patched.
Toward self-healing
In a truly optimistic future, we can imagine a self-healing network. AI agents continuously scan the ever-evolving corpus of commercial and custom AI-generated software for vulnerabilities, and automatically patch them on discovery.
For that to work, software license agreements will need to change. Right now, software vendors control the cadence of security patches. Giving software purchasers this ability has implications about compatibility, the right to repair, and liability. Any solutions here are the realm of policy, not tech.
If the defense can find, but can’t reliably patch, flaws in legacy software, that’s where attackers will focus their efforts. If that’s the case, we can imagine a continuously evolving AI-powered intrusion detection, continuously scanning inputs and blocking malicious attacks before they get to vulnerable software. Not as transformative as automatically patching vulnerabilities in running code, but nevertheless valuable.
The power of these defensive AI systems increases if they are able to coordinate with each other, and share vulnerabilities and updates. A discovery by one AI can quickly spread to everyone using the affected software. Again: Advantage defender.
There are other variables to consider. The relative success of attackers and defenders also depends on how plentiful vulnerabilities are, how easy they are to find, whether AIs will be able to find the more subtle and obscure vulnerabilities, and how much coordination there is among different attackers. All this comprises Unknown No. 4.
Vulnerability economics
Presumably, AIs will clean up the obvious stuff first, which means that any remaining vulnerabilities will be subtle. Finding them will take AI computing resources. In the optimistic scenario, defenders pool resources through information sharing, effectively amortizing the cost of defense. If information sharing doesn’t work for some reason, defense becomes much more expensive, as individual defenders will need to do their own research. But instant software means much more diversity in code: an advantage to the defender.
This needs to be balanced with the relative cost of attackers finding vulnerabilities. Attackers already have an inherent way to amortize the costs of finding a new vulnerability and create a new exploit. They can vulnerability hunt cross-platform, cross-vendor, and cross-system, and can use what they find to attack multiple targets simultaneously. Fixing a common vulnerability often requires cooperation among all the relevant platforms, vendors, and systems. Again, instant software is an advantage to the defender.
But those hard-to-find vulnerabilities become more valuable. Attackers will attempt to do what the major intelligence agencies do today: find “nobody but us” zero-day exploits. They will either use them slowly and sparingly to minimize detection or quickly and broadly to maximize profit before they’re patched. Meanwhile, defenders will be both vulnerability hunting and intrusion detecting, with the goal of patching vulnerabilities before the attackers find them.
We can even imagine a market for vulnerability sharing, where the defender who finds a vulnerability and creates a patch is compensated by everyone else in the information-sharing/repair network. This might be a stretch, but maybe.
Up the stack
Even in the most optimistic future, attackers aren’t going to just give up. They will attack the non-software parts of the system, such as the users. Or they’re going to look for loopholes in the system: things that the system technically allows but were unintended and unanticipated by the designers—whether human or AI—and can be used by attackers to their advantage.
What’s left in this world are attacks that don’t depend on finding and exploiting software vulnerabilities, like social engineering and credential stealing attacks. And we have already seen how AI-generated deepfakes make social engineering easier. But here, too, we can imagine defensive AI agents that monitor users’ behaviors, watching for signs of attack. This is another AI use case, and one that I’m not even sure how to think about in terms of the attacker/defender arms race. But at least we’re pushing attacks up the stack.
Also, attackers will attempt to infiltrate and influence defensive AIs and the networks they use to communicate, poisoning their output and degrading their capabilities. AI systems are vulnerable to all sorts of manipulations, such as prompt injection, and it’s unclear whether we will ever be able to solve that. This is Unknown No. 5, and it’s a biggie. There might always be a “trusting trust problem.”
No future is guaranteed. We truly don’t know whether these technologies will continue to improve and when they will plateau. But given the pace at which AI software development has improved in just the past few months, we need to start thinking about how cybersecurity works in this instant software world.
EDITED TO ADD: Twoessays published after I wrote this. Both are good illustrations of where we are re AI vulnerability discovery. Things are changing very fast.
Security is traditionally a game of defense. You build walls, set up gates, and write rules to block traffic that looks suspicious. For years, Cloudflare has been a leader in this space: our Application Security platform is designed to catch attacks in flight, dropping malicious requests at the edge before they ever reach your origin. But for API security, defensive posturing isn’t enough.
That’s why today, we are launching the beta of Cloudflare’s Web and API Vulnerability Scanner.
We are starting with the most pervasive and difficult-to-catch threat on the OWASP API Top 10: Broken Object Level Authorization, or BOLA. We will add more vulnerability scan types over time, including both API and web application threats.
The most dangerous API vulnerabilities today aren’t generic injection attacks or malformed requests that a WAF can easily spot. They are logic flaws—perfectly valid HTTP requests that meet the protocol and application spec but defy the business logic.
To find these, you can’t just wait for an attack. You have to actively hunt for them.
The Web and API Vulnerability Scanner will be available first for API Shield customers. Read on to learn why we are focused on API security scans for this first release.
Why purely defensive security misses the mark
In the web application world, vulnerabilities often look like syntax errors. A SQL injection attempt looks like code where data should be. A cross-site scripting (XSS) attack looks like a script tag in a form field. These have signatures.
API vulnerabilities are different. To illustrate, let’s imagine a food delivery mobile app that communicates solely with an API on the backend. Let’s take the orders endpoint:
Endpoint Definition: /api/v1/orders
Method
Resource Path
Description
GET
/api/v1/orders/{order_id}
Check Status. Returns the tracking status of a specific order (e.g., “Kitchen is preparing”).
PATCH
/api/v1/orders/{order_id}
Update Order. Allows the user to modify the drop-off location or add delivery instructions.
In a broken authorization attack like BOLA, User A (the attacker) requests to update the delivery address of a paid-for order belonging to User B (the victim). The attacker simply inserts User B’s {order_id} in the PATCH request.
Here is what that request looks like, with ‘8821’ as User B’s order ID. Notice that User A is fully authenticated with their own valid token:
PATCH /api/v1/orders/8821 HTTP/1.1
Host: api.example.com
Authorization: Bearer <User_A_Valid_Token>
Content-Type: application/json

{
  "delivery_address": "123 Attacker Way, Apt 4",
  "instructions": "Leave at front door, ring bell"
}
The request headers are valid. The authentication token is valid. The schema is correct. To a standard WAF, this request looks perfect. A bot management offering may even be fooled if a human is manually sending the attack requests.
User A will now get B’s food delivered to them! The vulnerability exists because the API endpoint fails to validate if User A actually has permission to view or update user B’s data. This is a failure of logic, not syntax. To fix this, the API developer could implement a simple check: if (order.userID != user.ID) throw Unauthorized;
You can detect these types of vulnerabilities by actively sending API test traffic or passively listening to existing API traffic. Finding these vulnerabilities through passive scanning requires context. Last year we launched BOLA vulnerability detection for API Shield. This detection automatically finds these vulnerabilities by passively scanning customer traffic for usage anomalies. To be successful with this type of scanning, you need to know what a “valid” API call looks like, what the variable parameters are, how a typical user behaves, and how the API behaves when those parameters are manipulated.
Yet there are reasons security teams may not have any of that context, even with access to API Shield’s BOLA vulnerability detection. Development environments may need to be tested but lack user traffic. Production environments may (thankfully) have a lack of attack traffic yet still need analysis, and so on. In these circumstances, and to be proactive in general, teams can turn to Dynamic Application Security Testing (DAST). By creating net-new traffic profiles intended specifically for security testing, DAST tools can look for vulnerabilities in any environment at any time.
Unfortunately, traditional DAST tools have a high barrier to entry. They are often difficult to configure, require you to manually upload and maintain Swagger/OpenAPI files, struggle to authenticate correctly against modern complex login flows, and can simply lack any API-specific security tests (e.g. BOLA).
Cloudflare’s API scanning advantage
In the food delivery order example above, we assumed the attacker could find a valid order to modify. While there are often avenues for attackers to gather this type of intelligence in a live production environment, in a security testing exercise you must create your own objects before testing the API’s authorization controls. For typical DAST scans, this can be a problem, because many scanners treat each individual request on its own. This method fails to chain requests together in the logical pattern necessary to find broken authorization vulnerabilities. Legacy DAST scanners can also exist as an island within your security tooling and orchestration environment, preventing their findings from being shared or viewed in context.
Vulnerability scanning from Cloudflare is different for a few key reasons.
First, Security Insights will list results from our new scans alongside any existing Cloudflare security findings for added context. You’ll see all your posture management information in one place.
Second,we already know your API’s inputs and outputs. If you are an API Shield customer, Cloudflare already understands your API. Our API Discovery and Schema Learning features passively catalog your endpoints and learn your traffic patterns. While you’ll need to manually upload an OpenAPI spec to get started for our initial release, you will be able to get started quickly without one in a future release.
Third, because we sit at the edge, we can turn passive traffic inspection knowledge into active intelligence. It will be easy to verify BOLA vulnerability detection risks (found via traffic inspection) by sending net-new HTTP requests with the vulnerability scanner.
And finally, we have built a new, stateful DAST platform, as we detail below. Most scanners require hours of setup to “teach” the tool how to talk to your API. With Cloudflare, you can effectively skip that step and get started quickly. You provide the API credentials, and we’ll use your API schemas to automatically construct a scan plan.
Building automatic scan plans
APIs are commonly documented using OpenAPI schemas. These schemas denote the host, method, and path (commonly, an “endpoint”) along with the expected parameters of incoming requests and resulting responses. In order to automatically build a scan plan, we must first make sense of these API specifications for any given API to be scanned.
Our scanner works by building up an API call graph from an OpenAPI document and subsequently walking it, using attacker and owner contexts. Owners create resources, attackers subsequently try to access them. Attackers are fully authenticated with their own set of valid credentials. If an attacker successfully reads, modifies or deletes an unowned resource, an authorization vulnerability is found.
Consider for example the above delivery order with ID 8821. For the server-side resource to exist, it needed to be originally created by an owner, most likely in a “genesis” POST request with no or minimal dependencies (previous necessary calls and resulting data). Modelling the API as a call graph, such an endpoint constitutes a node with no or few incoming edges (dependencies). Any subsequent request, such as the attacker’s PATCH above, then has a data dependency (the data is order_id) on the genesis request (the POST). Without all data provided, the PATCH cannot proceed.
Here we see in purple arrows the nodes in this API graph that are necessary to visit an order to add a note to an order via the POST /api/v1/orders/{order_id}/note/{note_id} endpoint. Importantly, none of the steps or logic shown in the diagram is available in the OpenAPI specification! It must be inferred logically through some other means, and that is exactly what our vulnerability scanner will do automatically.
In order to reliably and automatically plan scans across a variety of APIs, we must accurately model these endpoint relationships from scratch. However, two problems arise: data quality of API specifications is not guaranteed, and even functionally complete schemas can have ambiguous naming schemes. Consider a simplified OpenAPI specification for the above API, which might look like
openapi: 3.0.0
info:
  title: Order API
  version: 1.0.0
paths:
  /api/v1/orders:
    post:
      summary: Create an order
      requestBody:
        required: true
        content:
          application/json:
            schema:
              type: object
              properties:
                product:
                  type: string
                count:
                  type: integer
              required:
                - product
                - count
      responses:
        '201':
          description: Item created successfully
          content:
            application/json:
              schema:
                type: object
                properties:
                  result:
                    type: object
                    properties:
                      id:
                        type: integer
                      created_at:
                        type: integer
                  errors:
                    type: array
                    items:
                      type: string
  /api/v1/orders/{order_id}:
    patch:
      summary: Modify an order by ID
      parameters:
        - name: order_id
          in: path
We can see that the POST endpoint returns responses such as
To a human observer, it is quickly evident that $.result.id is the value to be injected in order_id for the PATCH endpoint. The id property might also be called orderId, value or something else, and be nested arbitrarily. These subtle inconsistencies in OpenAPI documents of arbitrary shape are intractable for heuristics-based approaches.
Our scanner uses Cloudflare’s own Workers AI platform to tackle this fuzzy problem space. Models such as OpenAI’s open-weight gpt-oss-120b are powerful enough to match data dependencies reliably, and to generate realistic fakedata where necessary, essentially filling in the blanks of OpenAPI specifications. Levering structured outputs, the model produces a representation of the API call graph for our scanner to walk, injecting attacker and owner credentials appropriately.
This approach tackles the problem of needing human intelligence to infer authorization and data relationships in OpenAPI schemas with artificial intelligence to do the same. Structured outputs bridge the gap from the natural language world of gpt-oss back to machine-executable instructions. In addition to Workers AI solving the planning problem, self-hosting on Workers AI means our system automatically benefits from Cloudflare’s highly available, globally distributed architecture.
Built on proven foundations
Building a vulnerability scanner that customers will trust with their API credentials demands proven infrastructure. We did not reinvent the wheel here. Instead, we integrated services that have been validated and deployed across Cloudflare for two crucial components of our scanner platform: the scanner’s control plane and the scanner’s secrets store.
The scanner’s control plane integrates with Temporal for Scan Orchestration, on which other internal services at Cloudflare already rely. The complexity of the numerous test plans executed in each Scan is effectively managed by Temporal’s durable execution framework.
The entire backend is written in Rust, which is widely adopted at Cloudflare for infrastructure services. This lets us reuse internal libraries and share architectural patterns across teams. It also positions our scanner for potential future integration with other Cloudflare systems like FL2 or our test framework Flamingo – enabling scenarios where scanning could coordinate more tightly with edge request handling or testing infrastructure.
Credential security through HashiCorp’s Vault Transit Secret Engine
Scanning for broken authentication and broken authorization vulnerabilities requires handling API user credentials. Cloudflare takes this responsibility very seriously.
We ensure that our public API layer has minimal access to unencrypted customer credentials by using HashiCorp’s Vault Transit Secret Engine (TSE) for encryption-as-a-service. Immediately upon submission, credentials are encrypted by TSE—which handles the encryption but does not store the ciphertext—and are subsequently stored on Cloudflare infrastructure.
Our API is not authorized to decrypt this data. Instead, decryption occurs only at the last stage when a TestPlan makes a request to the customer’s infrastructure. Only the Worker executing the test is authorized to request decryption, a restriction we strengthen using strict typing with additional safety rails inside Rust to enforce minimal access to decryption methods.
We further secure our customers’ credentials through regular rotation and periodic rewraps using TSE to mitigate risk. This process means we only interact with the new ciphertext, and the original secret is kept unviewable.
What’s next?
We are releasing BOLA vulnerability scanning starting today as an Open Beta for all API Shield customers, and are working on future API threat scans for future release. Via the Cloudflare API, you can trigger scans, manage configuration, and retrieve results programmatically to integrate directly into your CI/CD pipelines or security dashboards. For API Shield Customers: check the developer docs to start scanning your endpoints for BOLA vulnerabilities today.
We are starting with BOLA vulnerabilities because they are the hardest API vulnerability to solve and the highest risk for our customers. However, this scanning engine is built to be extensible.
In the near future, we plan to expand the scanner’s capabilities to cover the most popular of the OWASP Web Top 10 as well: classic web vulnerabilities like SQL injection (SQLi) and cross-site scripting (XSS). To be notified upon release, sign up for the waitlist here, and you’ll be first to learn when we expand the engine to general web application vulnerabilities.
Traditional Web Application Firewalls typically require extensive, manual tuning of their rules before they can safely block malicious traffic. When a new application is deployed, security teams usually begin in a logging-only mode, sifting through logs to gradually assess which rules are safe for blocking mode. This process is designed to minimize false positives without affecting legitimate traffic. It’s manual, slow and error-prone.
Teams are forced into a trade-off: visibility in log mode, or protection in block mode. When a rule blocks a request, evaluation stops, and you lose visibility into how other signatures would have assessed it — valuable insight that could have helped you tune and strengthen your defenses.
Today, we’re solving this by introducing the next evolution of our managed rules: Attack Signature Detection.
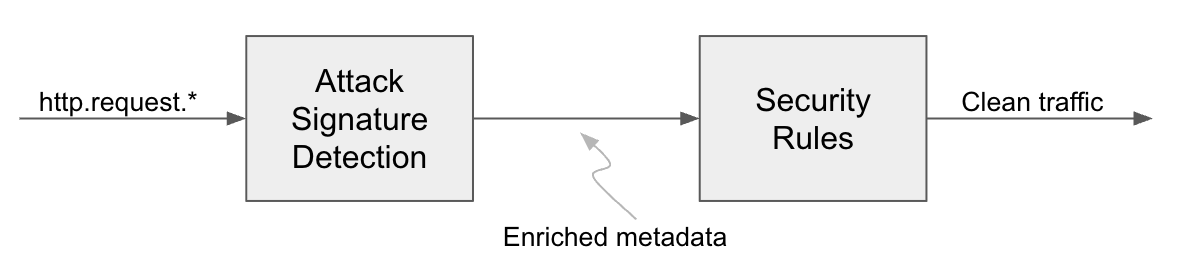
When enabled, this detection inspects every request for malicious payloads and attaches rich detection metadata before any action is taken. You get complete visibility into every signature match, without sacrificing protection or performance. Onboarding becomes simple: traffic is analyzed, data accumulates, and you see exactly which signatures fire and why. You can then build precise mitigation policies based on past traffic, reducing the risk of false positives.
But we’re going one step further. We’re moving beyond request-only analysis to something far more powerful: Full-Transaction Detection.
Instead of looking at just the incoming request, this new detection correlates the entire HTTP transaction: request and response. By analyzing the full context, we dramatically reduce false positives compared to traditional request-only signature engines. More importantly, we uncover threats others miss, such as reflective SQL injection, subtle data exfiltration patterns, and dangerous misconfigurations that only reveal themselves in the response.
Attack Signature Detection is available now in Early Access — sign up here to express interest. Full-Transaction Detection is under development; register here to be among the first to try it when it’s ready.
The always-on framework
To provide full visibility on your traffic without slowing down the Internet, we had to change how we think about the request lifecycle. For customers who opt in, Attack Signature detection is now “always on.” This means that as soon as traffic is proxied, all detection signatures are executed on every request, and the results are immediately visible in Security Analytics.
This “always-on” framework separates detection from mitigation. Detections run continuously, enriching analytics with metadata about triggered detections. This metadata is also added to the request as a new field, which customers can use to create custom policies within security rules.
Separating the detection of malicious payloads from the actions taken by security rules is the core of the always-on framework. This approach enhances the analytics experience and increases confidence when deploying new protections.
Our existing Bot Score and Attack Score detections already follow this method. Attack Signature Detection provides the same coverage as our Managed Rules product but operates within this new framework.
Does this introduce additional latency to the request? No — this model is designed for efficiency. If a customer has not created a blocking rule based on a detection, the detection can be executed after the request has been sent to the origin server, ensuring that the detection itself introduces no additional latency to the traffic. Therefore, upon onboarding, the detection is enabled by default but does not impact traffic performance. When a rule is created, the detection is moved in-line with the request that might experience additional latency. The exact value depends on the traffic profile of the application.
Attack Signature Detection
Compared to traditional, rule-based systems like the Cloudflare Managed Ruleset, the new detection offers a substantial advancement in web application security. This approach makes identifying malicious web payloads and deploying security rules significantly more user-friendly.
The Cloudflare Managed Ruleset is where our analyst team develops detections for common attack vectors, including SQL injection (SQLi), Cross Site Scripting (XSS), Remote Code Execution (RCE), and specific Common Vulnerabilities and Exposures (CVEs). Analysts typically release new rules weekly, with emergency releases deployed for high-profile vulnerabilities (such as the recent React2Shellrelease). Currently, over 700 managed rules are active in our Managed Ruleset. The new detections are also known as signature rules or simply signatures. They employ the same heuristics as Managed Rules but do not directly apply actions to traffic.
Each signature is uniquely identified by a Ref ID (similar to the Rule ID for the Managed Ruleset) and is tagged with both category and confidence. The category specifies the attack vectors the signature targets, while the confidence level indicates the likelihood of a false positive (a trigger on legitimate traffic). A rule can have only one confidence level but may have multiple categories.
Category indicates what attack vector the rule refers to. The list of categories is long, but includes tags like SQLi, XSS, RCE or specific CVE with its number.
The confidence field is divided into two values, based on whether at least one signature from the corresponding group matches the traffic.
Confidence
Description
High
These signatures aim for high true positives and low false positives, typical for CVEs where payloads are identifiable without blocking legitimate traffic. They function like the Managed Ruleset’s default configuration.
Medium
These signatures, which are turned off by default in the Managed Ruleset, may cause false positives based on your traffic. Before blocking traffic matching these rules, assess their potential application impact.
The detection’s analysis of a request populates three fields. These fields are accessible in Security Analytics and Edge Rules Engine, our core engine for Security Rules.
Field
Description
Where can be used
cf.waf.signature.request.confidence
Array. Aggregate the confidence scores associated with the matching signatures.
Analytics and Security Rules
cf.waf.signature.request.categories
Array. Aggregate the categories associated with the matching signatures.
Analytics and Security Rules
cf.waf.signature.request.ref
Array. Aggregates the Ref IDs of the matching signatures, up to 10.
Analytics and Security Rules
Analyzing your data in Security Analytics
Security Analytics is at the core of the Cloudflare Application Security toolbox, providing a comprehensive, data-driven view of how signatures interact with your web traffic. It gives you the tools necessary to understand, measure, and optimize your web protection. Common use cases for combining Analytics with signatures include: design a security posture during the onboarding process, verify the most frequent attack attempts and create exceptions to handle false positives.
Once a new application is proxied through Cloudflare, Attack Signature Detection begins populating your dashboard with data. The initial step is to examine the aggregated matches, categorized by type and signature, to confirm that all potential attacks are being blocked. Analysts can do this by reviewing the top statistics for signatures, filtering the data to show whether requests were blocked, served from the cache, or permitted to reach the origin server. If any malicious requests are found to have reached the origin, analysts can quickly implement security rules.
A breakdown of the total request volume matching attack signatures, categorized by their corresponding Category or Signature.
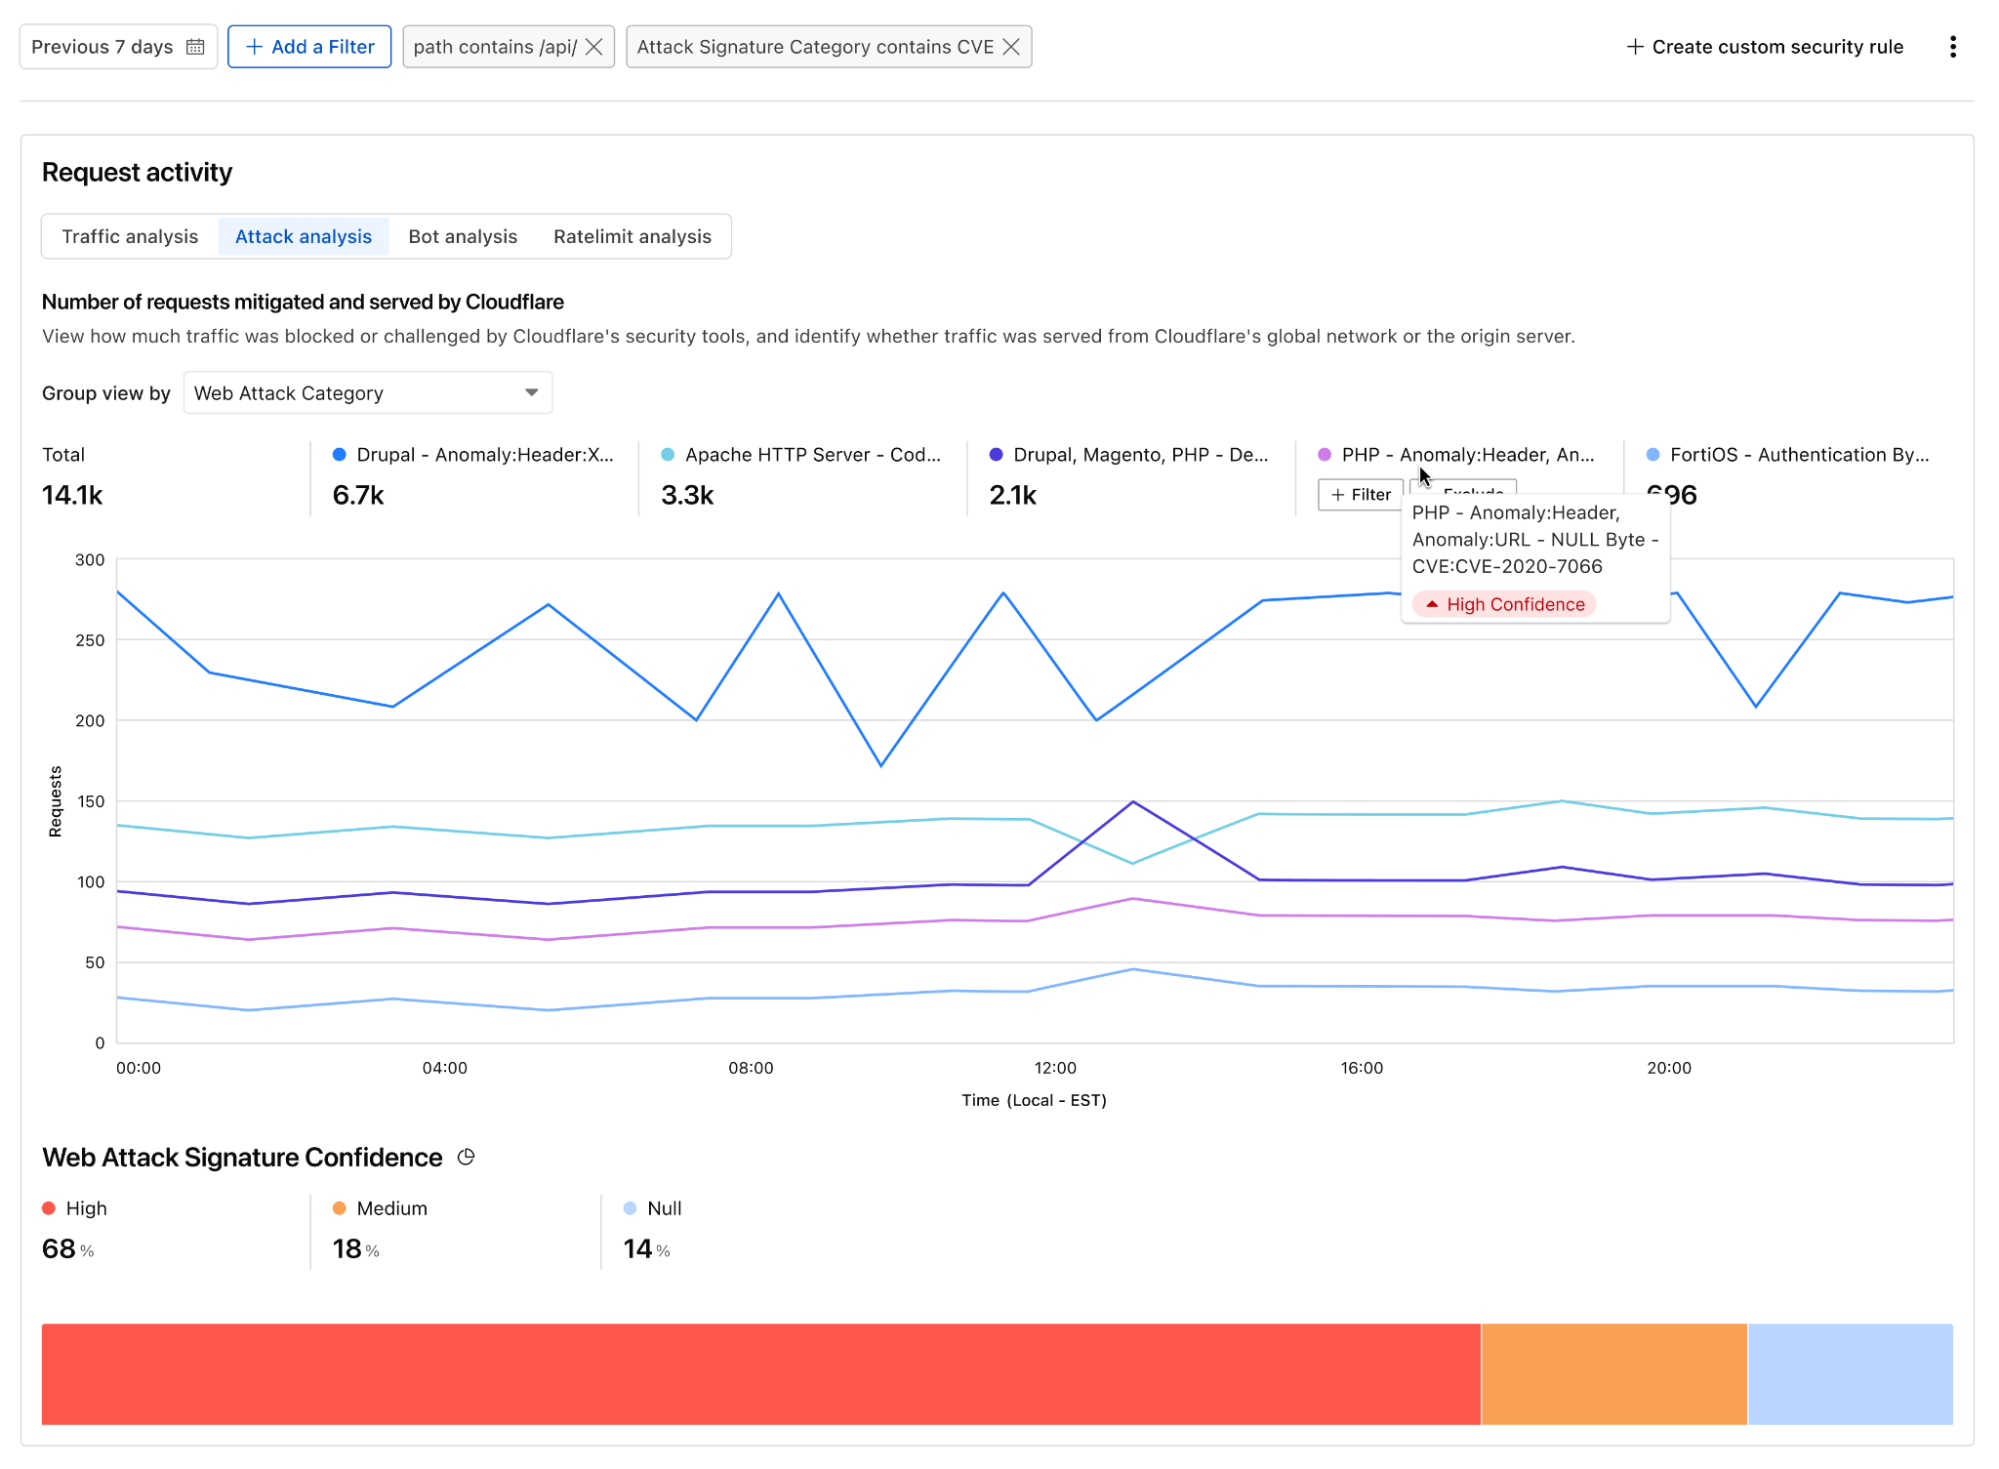
Analytics provides insights into attack patterns, such as the most frequent CVEs based on traffic volume over time. This capability is designed for quickly identifying the dominant attack payloads targeting applications and verifying the efficacy of current protections against related CVEs. For example, analysts can monitor the attack frequency targeting a specific part of the application, like /api/, or confirm if known malicious payloads, such as React2Shell, are reaching a particular endpoint, such as the POST /_next/ Node.js path. Both the Analytics filters and the Attack Analysis tool can be used to perform this type of investigation.
A visualization within Security Analytics offers a time-series view of malicious payloads targeting the /api/ endpoint. This view groups the data to highlight the top five CVEs by volume.
Analytics also help create exceptions and identifying false positives. An increase in matches for a specific rule, for instance, may suggest false positives rather than active exploitation. For example, an application that allows users to submit rich HTML content (such as a Content Management Systems or support ticketing system) may legitimately include markup that matches more generic XSS signatures. In these cases, a scoped exception can be applied to the affected endpoint, while keeping the protection enabled across the rest of the application.
This approach is especially useful for evaluating medium-confidence signatures, which balance aggressive blocking with false-positive risk. The tool allows “what-if” scenarios against historical traffic to empirically determine production performance. This process helps determine if a medium-confidence signature is appropriate for the overall traffic profile, or if a high rate of false positives requires limiting its deployment to specific URLs or request types.
Generally, signatures that have a very low match rate on historical traffic can be more safely deployed in block mode without significant disruption to legitimate traffic. To achieve this level of confidence, Security Analytics provides the tools for in-depth forensics investigations.
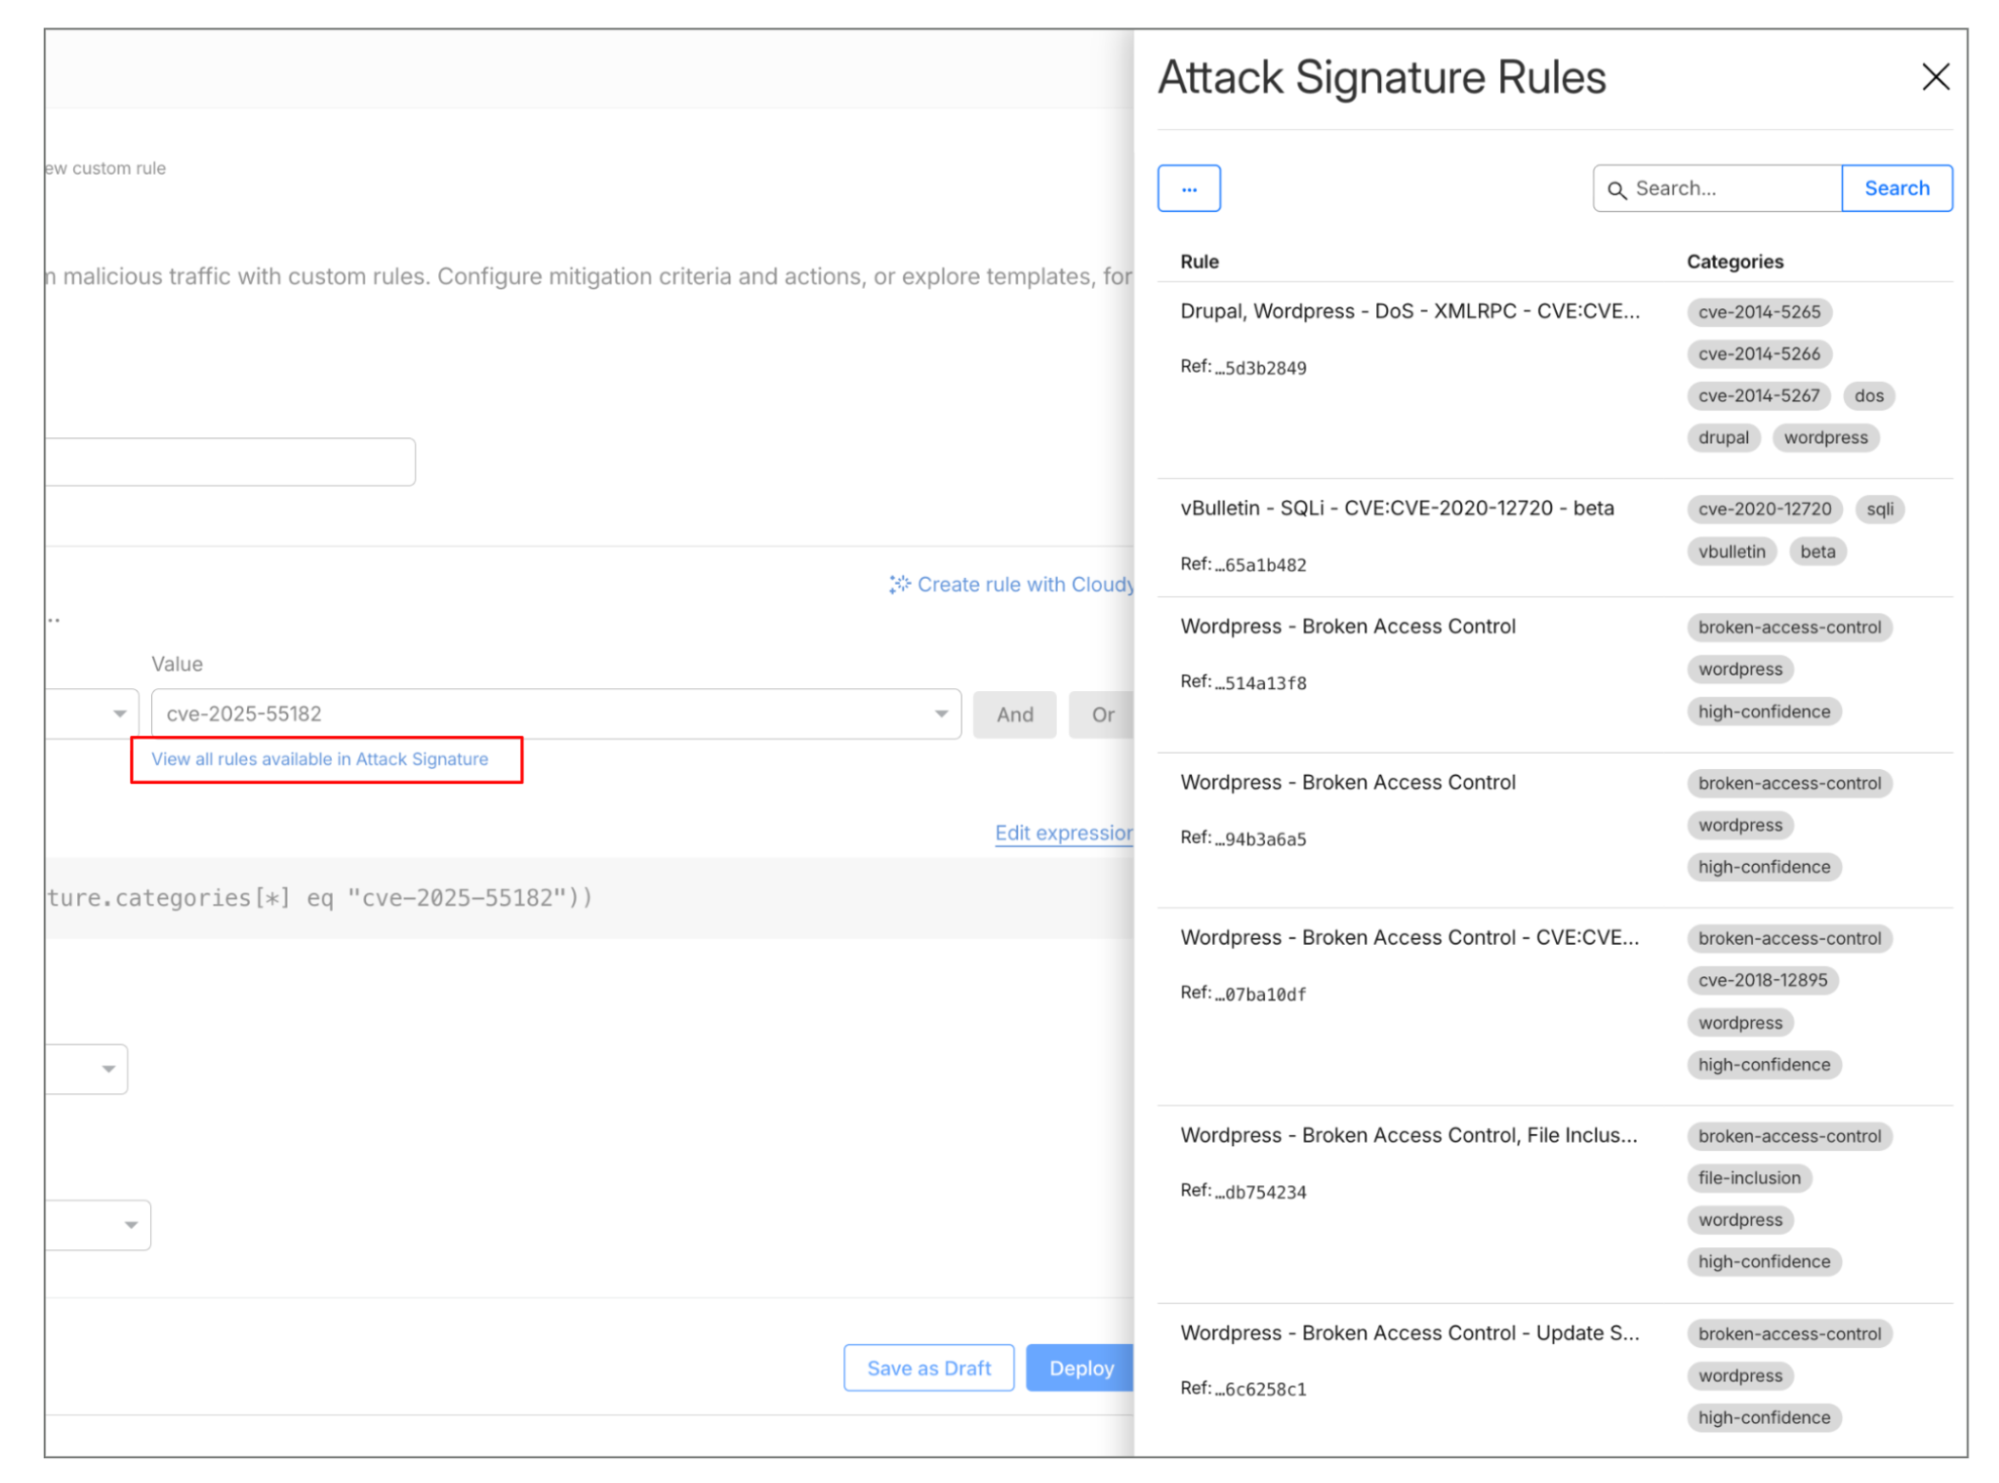
Beyond immediate detection, a crucial aspect of defense management is the ability to customize your security posture. The user interface offers a searchable catalog of all security signatures, allowing you to browse the full list and understand the specific threat each is designed to address.
A searchable catalog of signatures is available, providing more detail on critical detections to help customers understand the threats and the remediation actions.
Creating security rules
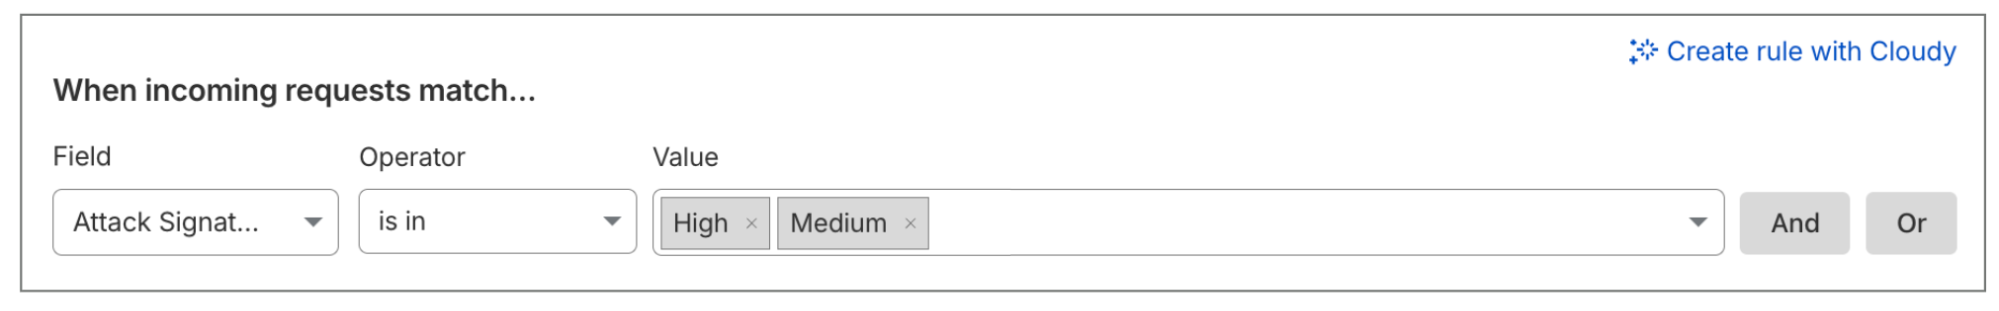
After analyzing your data and establishing confidence in how the signatures performed against your past traffic, you can easily create custom rules to handle traffic based on the detections. For example, if you want to create a policy that blocks requests matching high confidence signatures you can create the following rule:
Creating a rule to block requests matching with high confidence signatures.
This is equivalent to the Cloudflare Managed Ruleset default deployment.
If you want to block all requests matching at least one rule, you will add the Medium confidence tag. This is equivalent to enabling all rules of Cloudflare Managed Ruleset. Alternatively, you can configure multiple rules, applying a more stringent action (like “Block”) for detections with High confidence and a less strict action (such as “Challenge”) for those with Medium confidence.
By selecting both High and Medium confidence you can trigger a rule if any signature matches.
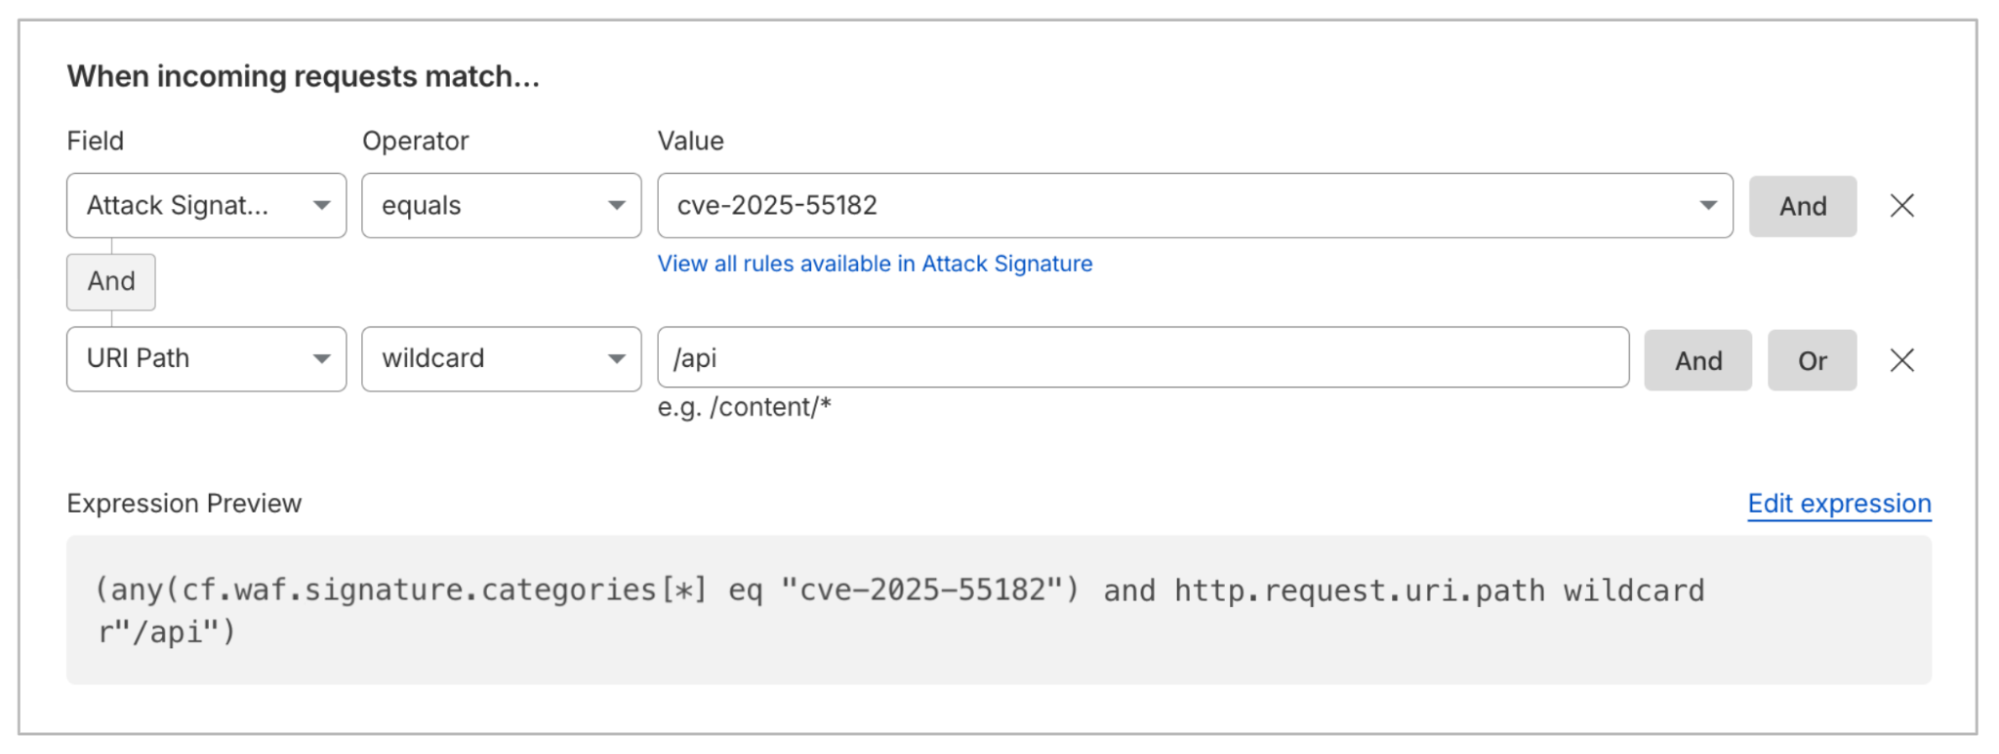
To create a rule blocking a specific CVE or attack vector, you will use Categories. The rule builder allows you to combine attack vector category tags with all existing HTTP request data. This enables you to create granular rules (or exceptions) and tailor your security posture to different parts of your application.
Customers can create rules to block (or allow) requests matching specific CVEs or attack categories.
To create rules based on a specific Signature, you can use Ref ID. You can find the right Ref ID within the rule builder by exploring the available Attack Signature rules. This is especially useful if you want to create exceptions to manage false positives.
Customers can browse signature rules directly from the rule builder.
What happens to Cloudflare Managed Ruleset?
All customers continue to have access to our classic Managed Ruleset. When Attack Signature Detection is broadly available, customers will be able to choose the deployment model that best suits their needs, whether that is Attack Signature Detection or Managed Rules. Our analyst teams ensure that new detections are released simultaneously across both the Managed Ruleset and Attack Signature Detection.
Full-Transaction Detection
Traditional web attack detection primarily focuses on the “ask”: the HTTP request. However, the request only tells half the story. To know if an attack actually succeeded, you have to look at the “answer”: the HTTP response.
By combining request and response metadata into a single detection event, we can dramatically reduce false positives and identify successful exploits that request-only systems miss.
For example, consider a request containing a common SQL injection string in a query parameter.
GET /user?id=1' UNION SELECT username, password FROM users--
A traditional WAF will see the UNION SELECT pattern and block it. However, if the application isn’t actually vulnerable, this might be a false positive — for instance a security researcher testing their own site.
With Full-Transaction Detection, the system notes the SQLi signature in the request but waits for the response. If the origin responds with a 500 Internal Server Error or a standard 404, the confidence of a “successful exploit” is low. If the origin responds with a 200 OK and a body containing a string that matches a “sensitive data” signature (like a list of usernames), the system flags a Successful Exploit Confirmation.
To start, we are rolling out a few detection categories and plan to expand this list over time. Here are the three areas we are currently focused on, and some of the flags you’ll see:
Exploit attempts. The detection provides web attack detections by inspecting the entire HTTP request-to-response cycle. It focuses on three key areas: identifying input exploitation like XSS and SQLi via malicious signatures, stopping automated abuse such as vulnerability probing, and confirming successful exploits by correlating suspicious requests with unusual server responses.
Data exposure and exfiltration signals. This framework also allows us to catch data exfiltration that looks like legitimate traffic on the way in. A request for /api/v1/export is a standard administrative action. But if that specific request triggers a response containing 5,000 credit card numbers (for example identified via Luhn algorithm signatures), the transaction is flagged as Data Exposure.
Misconfigurations. Exposed admin interfaces are often attack vectors. Traditional security checks miss this misconfiguration because the traffic itself looks valid (real endpoints or admin pages). The issue isn’t the traffic but its public accessibility. We prioritize detection based on common real-world misconfigurations seen in customer data, such as public unauthenticated Elasticsearch clusters, Internet reachable admin panels, and exposed Apache sensitive endpoints.
The detection, much like Attack Signatures, will store the results in two specific fields. These fields are accessible in our dashboard and logged within Security Analytics.
Field
Description
Where can be used
cf.waf.signature.response.categories
Array. Aggregate the categories associated with the matching signatures.
Security Analytics
cf.waf.signature.response.ref
Array. Aggregates the Ref IDs of the matching signatures, up to 10.
Security Analytics
Initially, we are focused on offering visibility into matching requests via analytics. By surfacing events on potential exploits, we provide customers information that can be used for incident response through targeted remediations across their infrastructure and software stack. Our future plans include extending Security Rules to the response phase, which will empower customers to block responses based on these detections by allowing policy creation.
A diagram illustrating the execution locations and corresponding populated fields for both Attack Signature Detection and Full-Transaction Detection.
Sign up to get access
Attack Signature detection is in Early Access while Full-Transaction Detection is under development. Sign up here to get access to Attack Signature, and here to express interest for Full-Transaction. We’ll gather feedback in the coming months as we prepare these features for General Availability.
In the latest OpenSSL security release> on January 27, 2026, twelve new zero-day vulnerabilities (meaning unknown to the maintainers at time of disclosure) were announced. Our AI system is responsible for the original discovery of all twelve, each found and responsibly disclosed to the OpenSSL team during the fall and winter of 2025. Of those, 10 were assigned CVE-2025 identifiers and 2 received CVE-2026 identifiers. Adding the 10 to the three we already found in the Fall 2025 release, AISLE is credited for surfacing 13 of 14 OpenSSL CVEs assigned in 2025, and 15 total across both releases. This is a historically unusual concentration for any single research team, let alone an AI-driven one.
These weren’t trivial findings either. They included CVE-2025-15467, a stack buffer overflow in CMS message parsing that’s potentially remotely exploitable without valid key material, and exploits for which have been quickly developed online. OpenSSL rated it HIGH severity; NIST‘s CVSS v3 score is 9.8 out of 10 (CRITICAL, an extremely rare severity rating for such projects). Three of the bugs had been present since 1998-2000, for over a quarter century having been missed by intense machine and human effort alike. One predated OpenSSL itself, inherited from Eric Young’s original SSLeay implementation in the 1990s. All of this in a codebase that has been fuzzed for millions of CPU-hours and audited extensively for over two decades by teams including Google’s.
In five of the twelve cases, our AI system directly proposed the patches that were accepted into the official release.
AI vulnerability finding is changing cybersecurity, faster than expected. This capability will be used by both offense and defense.
In a recent evaluation of AI models’ cyber capabilities, current Claude models can now succeed at multistage attacks on networks with dozens of hosts using only standard, open-source tools, instead of the custom tools needed by previous generations. This illustrates how barriers to the use of AI in relatively autonomous cyber workflows are rapidly coming down, and highlights the importance of security fundamentals like promptly patching known vulnerabilities.
[…]
A notable development during the testing of Claude Sonnet 4.5 is that the model can now succeed on a minority of the networks without the custom cyber toolkit needed by previous generations. In particular, Sonnet 4.5 can now exfiltrate all of the (simulated) personal information in a high-fidelity simulation of the Equifax data breach—one of the costliest cyber attacks in historyusing only a Bash shell on a widely-available Kali Linux host (standard, open-source tools for penetration testing; not a custom toolkit). Sonnet 4.5 accomplishes this by instantly recognizing a publicized CVE and writing code to exploit it without needing to look it up or iterate on it. Recalling that the original Equifax breach happened by exploiting a publicized CVE that had not yet been patched, the prospect of highly competent and fast AI agents leveraging this approach underscores the pressing need for security best practices like prompt updates and patches.
AI models are getting better at this faster than I expected. This will be a major power shift in cybersecurity.
In a recent evaluation of AI models’ cyber capabilities, current Claude models can now succeed at multistage attacks on networks with dozens of hosts using only standard, open-source tools, instead of the custom tools needed by previous generations. This illustrates how barriers to the use of AI in relatively autonomous cyber workflows are rapidly coming down, and highlights the importance of security fundamentals like promptly patching known vulnerabilities.
[…]
A notable development during the testing of Claude Sonnet 4.5 is that the model can now succeed on a minority of the networks without the custom cyber toolkit needed by previous generations. In particular, Sonnet 4.5 can now exfiltrate all of the (simulated) personal information in a high-fidelity simulation of the Equifax data breach—one of the costliest cyber attacks in history—using only a Bash shell on a widely-available Kali Linux host (standard, open-source tools for penetration testing; not a custom toolkit). Sonnet 4.5 accomplishes this by instantly recognizing a publicized CVE and writing code to exploit it without needing to look it up or iterate on it. Recalling that the original Equifax breach happened by exploiting a publicized CVE that had not yet been patched, the prospect of highly competent and fast AI agents leveraging this approach underscores the pressing need for security best practices like prompt updates and patches.
Read the whole thing. Automatic exploitation will be a major change in cybersecurity. And things are happening fast. There have been significant developments since I wrote this in October.
On October 13, 2025, security researchers from FearsOff identified and reported a vulnerability in Cloudflare’s ACME (Automatic Certificate Management Environment) validation logic that disabled some of the WAF features on specific ACME-related paths. The vulnerability was reported and validated through Cloudflare’s bug bounty program.
The vulnerability was rooted in how our edge network processed requests destined for the ACME HTTP-01 challenge path (/.well-known/acme-challenge/*).
Here, we’ll briefly explain how this protocol works and the action we took to address the vulnerability.
Cloudflare has patched this vulnerability and there is no action necessary for Cloudflare customers. We are not aware of any malicious actor abusing this vulnerability.
How ACME works to validate certificates
ACME is a protocol used to automate the issuance, renewal, and revocation of SSL/TLS certificates. When an HTTP-01 challenge is used to validate domain ownership, a Certificate Authority (CA) will expect to find a validation token at the HTTP path following the format of http://{customer domain}/.well-known/acme-challenge/{token value}.
If this challenge is used by a certificate order managed by Cloudflare, then Cloudflare will respond on this path and provide the token provided by the CA to the caller. If the token provided does not correlate to a Cloudflare managed order, then this request would be passed on to the customer origin, since they may be attempting to complete domain validation as a part of some other system. Check out the flow below for more details — other use cases are discussed later in the blog post.
The underlying logic flaw
Certain requests to /.well-known/acme-challenge/* would cause the logic serving ACME challenge tokens to disable WAF features on a challenge request, and allow the challenge request to continue to the origin when it should have been blocked.
Previously, when Cloudflare was serving a HTTP-01 challenge token, if the path requested by the caller matched a token for an active challenge in our system, the logic serving an ACME challenge token would disable WAF features, since Cloudflare would be directly serving the response. This is done because those features can interfere with the CA’s ability to validate the token values and would cause failures with automated certificate orders and renewals.
However, in the scenario that the token used was associated with a different zone and not directly managed by Cloudflare, the request would be allowed to proceed onto the customer origin without further processing by WAF rulesets.
How we mitigated this vulnerability
To mitigate this issue, a code change was released. This code change only allows the set of security features to be disabled in the event that the request matches a valid ACME HTTP-01 challenge token for the hostname. In that case, Cloudflare has a challenge response to serve back.
Cloudflare customers are protected
As we noted above, Cloudflare has patched this vulnerability and Cloudflare customers do not need to take any action. In addition, we are not aware of any malicious actor abusing this vulnerability.
Moving quickly with vulnerability transparency
As always, we thank the external researchers for responsibly disclosing this vulnerability. We encourage the Cloudflare community to submit any identified vulnerabilities to help us continually improve the security posture of our products and platform.
We also recognize that the trust you place in us is paramount to the success of your infrastructure on Cloudflare. We consider these vulnerabilities with the utmost concern and will continue to do everything in our power to mitigate impact. We deeply appreciate your continued trust in our platform and remain committed not only to prioritizing security in all we do, but also acting swiftly and transparently whenever an issue does arise.
We discovered a critical vulnerability (CVE-2026-21858, CVSS 10.0) in n8n that enables attackers to take over locally deployed instances, impacting an estimated 100,000 servers globally. No official workarounds are available for this vulnerability. Users should upgrade to version 1.121.0 or later to remediate the vulnerability.
On December 3, 2025, immediately following the public disclosure of the critical, maximum-severity React2Shell vulnerability (CVE-2025-55182), the Cloudforce One Threat Intelligence team began monitoring for early signs of exploitation. Within hours, we observed scanning and active exploitation attempts, including traffic originating from infrastructure associated with Asian-nexus threat groups.
Early activity indicates that threat actors quickly integrated this vulnerability into their scanning and reconnaissance routines. We observed systematic probing of exposed systems, testing for the flaw at scale, and incorporating it into broader sweeps of Internet‑facing assets. The identified behavior reveals the actors relied on a combination of tools, such as standard vulnerability scanners and publicly accessible Internet asset discovery platforms, to find potentially vulnerable React Server Components (RSC) deployments exposed to the Internet.
Patterns in observed threat activity also suggest that the actors focused on identifying specific application metadata — such as icon hashes, SSL certificate details, or geographic region identifiers — to refine their candidate target lists before attempting exploitation.
In addition to React2Shell, two additional vulnerabilities affecting specific RSC implementations were disclosed: CVE-2025-55183 and CVE-2025-55184. Both vulnerabilities, while distinct from React2Shell, also relate to RSC payload handling and Server Function semantics, and are described in more detail below.
On December 3, 2025, the React Team disclosed a Remote Code Execution (RCE) vulnerability affecting servers using the React Server Components (RSC) Flight protocol. The vulnerability, CVE-2025-55182, received a CVSS score of 10.0 and has been informally referred to as React2Shell.
The underlying cause of the vulnerability is an unsafe deserialization flaw in the RSC Flight data-handling logic. When a server processes attacker-controlled payloads without proper validation, it becomes possible to influence server-side execution flow. In this case, crafted input allows an attacker to inject logic that the server interprets in a privileged context.
Exploitation is straightforward. A single, specially crafted HTTP request is sufficient; there is no authentication requirement, user interaction, or elevated permissions involved. Once successful, the attacker can execute arbitrary, privileged JavaScript on the affected server.
This combination of authenticated access, trivial exploitation, and full code execution is what places CVE-2025-55182 at the highest severity level and makes it significant for organizations relying on vulnerable versions of React Server Components.
In response, Cloudflare has deployed new rules across its network, with the default action set to Block. These new protections are included in both the Cloudflare Free Managed Ruleset (available to all Free customers) and the standard Cloudflare Managed Ruleset (available to all paying customers), as detailed below. More information about the different rulesets can be found in our documentation.
CVE
Description
Cloudflare WAF Rule ID
CVE-2025-55182
React – RCE
Rules to mitigate React2Shell Exploit
Paid: 33aa8a8a948b48b28d40450c5fb92fba
Free: 2b5d06e34a814a889bee9a0699702280
CVE-2025-55182 – 2
React – RCE Bypass
Additional rules to mitigate exploit bypass
Paid: bc1aee59731c488ca8b5314615fce168
Free: cbdd3f48396e4b7389d6efd174746aff
CVE-2025-55182
Scanner Detection
Additional paid WAF rule to catch React2Shell scanning attempts
Paid: 1d54691cb822465183cb49e2f562cf5c
Recently disclosed RSC vulnerabilities
In addition to React2Shell, two additional vulnerabilities affecting specific RSC implementations were disclosed. The two vulnerabilities, while distinct from React2Shell, also relate to RSC payload handling and Server Function semantics, with corresponding Cloudflare protections noted below:
CVE
Description
Cloudflare WAF Rule ID
CVE-2025-55183
Leaking Server Functions
In deployments where Server Function identifiers are insufficiently validated, an attacker may force the server into returning the source body of a referenced function
Paid: 17c5123f1ac049818765ebf2fefb4e9b
Free: 3114709a3c3b4e3685052c7b251e86aa
CVE-2025-55184
React Function DoS
A crafted RSC Flight Payload containing cyclical Promise references can trigger unbounded recursion or event-loop lockups under certain server configurations, resulting in denial-of-service conditions
Paid: 2694f1610c0b471393b21aef102ec699
Investigation of early scanning and exploitation
The following analysis details the initial wave of activity observed by Cloudforce One, focusing on threat actor attempts to scan for and exploit the React2Shell vulnerability. While these findings represent activity immediately following the vulnerability’s release, and were focused on known threat actors, it is critical to note that the volume and scope of related threat activity have expanded dramatically since these first observations.
Tactics
Unsurprisingly, the threat actors were relying heavily on publicly available, commercial, and a variety of other tools to identify vulnerable servers:
Vulnerability intelligence: The actors leveraged vulnerability intelligence databases that aggregated CVEs, advisories, and exploits for tracking and prioritization.
Vulnerability reconnaissance: The actors conducted searches using large-scale reconnaissance services, indicating they are relying on Internet-wide scanning and asset discovery platforms to find exposed systems running React App or RSC components. They also made use of tools that identify the software stack and technologies used by websites.
Vulnerability scanning: Activity included use of Nuclei (User-Agent: Nuclei – CVE-2025-55182), a popular rapid scanning tool used to deploy YAML-based templates to check for vulnerabilities. The actors were also observed using a highly likely React2Shell scanner associated with the User-Agent “Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 React2ShellScanner/1.0.0“.
Vulnerability exploitation: The actors made use of Burp Suite, a web application security testing platform for identifying and exploiting vulnerabilities in HTTP/S traffic.
Techniques
Recon via Internet-wide scanning and asset discovery platform
To enumerate potential React2Shell targets, the actors leveraged an Internet-wide scanning and asset-discovery platform commonly used to fingerprint web technologies at scale. Their queries demonstrated a targeted effort to isolate React and Next.js applications — two frameworks directly relevant to the vulnerability — by searching for React-specific icon hashes, framework-associated metadata, and page titles containing React-related keywords. This approach likely allowed them to rapidly build an inventory of exploitable hosts before initiating more direct probing.
Targeting enumeration and filtering
During their reconnaissance phase, the operators applied additional filtering logic to refine their target set and minimize noise. Notably, they excluded Chinese IP space from their searches, indicating that their enumeration workflow intentionally avoided collecting data on possibly domestic infrastructure. They also constrained scanning to specific geographic regions and national networks to identify likely high-value hosts. Beyond basic fingerprinting, the actors leveraged SSL certificate attributes — including issuer details, subject fields, and top-level domains — to surface entities of interest, such as government or critical-infrastructure systems using .gov or other restricted TLDs. This combination of geographic filtering and certificate-based pivoting enabled a more precise enumeration process that prioritized strategically relevant and potentially vulnerable high-value targets.
Preliminary target analysis
Observed activity reflected a clear focus on strategically significant organizations across multiple regions. Their highest-density probing occurred against networks in Taiwan, Xinjiang Uygur, Vietnam, Japan, and New Zealand — regions frequently associated with geopolitical intelligence collection priorities. Other selective targeting was also observed against entities across the globe, including government (.gov) websites, academic research institutions, and critical‑infrastructure operators. These infrastructure operators specifically included a national authority responsible for the import and export of uranium, rare metals, and nuclear fuel.
The actors also prioritized high‑sensitivity technology targets such as enterprise password managers and secure‑vault services, likely due to their potential to provide downstream access to broader organizational credentials and secrets.
Additionally, the campaign targeted edge‑facing SSL VPN appliances whose administrative interfaces may incorporate React-based components, suggesting the actor sought to exploit React2Shell against both traditional web applications and embedded web management frameworks in order to maximize access opportunities.
Early threat actor observations
Cloudforce One analysis confirms that early scanning and exploitation attempts originated from IP addresses previously associated with multiple Asia-affiliated threat actor clusters. While not all observed IP addresses belong to a single operator, the simultaneous activity suggests shared tooling, infrastructure, or experimentation in parallel among groups with a common purpose and shared targeting objectives. Observed targeting enumeration and filtering (e.g. a focus on Taiwan and Xinjiang Uygur, but exclusion of China), as well as heavy use of certain scanning and asset discovery platforms, suggest general attribution to Asia-linked threat actors.
Overall trends
Cloudflare’s Managed Rulesets for React2Shell began detecting significant activity within hours of the vulnerability’s disclosure. The graph below shows the daily hit count across the two exploit-related React2Shell WAF rules.
Aggregate rule hit volume over time
The React2Shell disclosure triggered a surge of opportunistic scanning and exploit behavior. In total, from 2025-12-03 00:00 UTC to 2025-12-11 17:00UTC, we received 582.10M hits. That equates to an average of 3.49M hits per hour, with a maximum number of hits in a single hour reaching 12.72M. The average unique IP count per hour was 3,598, with the maximum number of IPs in an hour being 16,585.
Hourly count of unique IPs sending React2Shell-related probes
Our data also shows distinct peaks above 6,387 User-Agents per hour, indicating a heterogeneous mix of tools and frameworks in use, with the average number of unique User-Agents per hour being 2,255. The below graph shows exploit attempts based on WAF rules (Free and Managed) triggering on matching payloads:
Unique User-Agent strings used in React2Shell-related requests
To better understand the types of automated tools probing for React2Shell exposure, Cloudflare analyzed the User-Agent strings associated with React2Shell-related requests since December 3, 2025. The data shows a wide variety of scanning tools suggesting broad Internet-wide reconnaissance:
Top 10 User Agent strings by exploit attempts
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 Assetnote/1.0.0
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 (GIS – AppSec Team – Project Vision)
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36
python-requests/2.32.5
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 Assetnote/1.0.0 (ExposureScan)
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/142.0.0.0 Safari/537.36
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36
Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/605.1.15 (KHTML, like Gecko) Version/18.1 Safari/605.1.1
Payload variation and experimentation
Cloudflare analyzed the payload sizes associated with requests triggering React2Shell-related detection rules. The long-tailed distribution — dominated by sub-kilobyte probes, but punctured by extremely large outliers — suggest actors are testing a wide range of payload sizes:
Metric
Value
Maximum payload size
375 MB
Average payload size
3.2 KB
p25 (25th Percentile)
703 B
p75 (75th Percentile)
818 B
p90 (90th Percentile)
2.7 KB
p99 (99th Percentile)
66.5 KB
Standard deviation
330 KB
Additional React vulnerabilities identified
In parallel with our ongoing analysis of the React2Shell vulnerability, two additional vulnerabilities affecting React Server Components (RSC) implementations have been identified:
1. React function DoS
The vulnerability CVE-2025-55184 was recently disclosed, revealing that React Server Component frameworks can be forced into a Node.js state where the runtime unwraps an infinite recursion of nested Promises.
This behavior:
Freezes the server indefinitely
Prevents yielding back to the event loop
Effectively takes the server offline
Does not require any specific Server Action usage — merely the presence of a server capable of processing an RSC Server Action payload
The trigger condition is a cyclic promise reference inside the RSC payload.
2. Leaking server functions
Another vulnerability, CVE-2025-55183, was also recently disclosed, revealing that certain React Server Component frameworks can leak server-only source code under specific conditions.
If an attacker gains access to a Server Function that:
Accepts an argument that undergoes string coercion, and
Does not validate that the argument is of an expected primitive type
then the attacker can coerce that argument into a reference to a different Server Function. The coerced value’s toString() output causes the server to return the source code of the referenced Server Function.
How Cloudflare is protecting customers
Cloudflare’s protection strategy is multi-layered, relying on both the inherent security model of its platform and immediate, proactive updates to its Web Application Firewall (WAF).
Cloudflare Workers: React-based applications and frameworks deployed on Cloudflare Workers are inherently immune. The Workers security model prevents exploits from succeeding at the runtime layer, regardless of the malicious payload.
Proactive WAF deployment: Cloudflare urgently deployed WAF rules to detect and block traffic proxied through its network related to React2Shell and the recently disclosed RSC vulnerabilities.
The Cloudflare security team continues to monitor for additional attack variations and will update protections as necessary to maintain continuous security for all proxied traffic.
Continuous monitoring
While Cloudflare’s emergency actions — the WAF limit increase and immediate rule deployment — have successfully mitigated the current wave of exploitation attempts, this vulnerability represents a persistent and evolving threat. The immediate weaponization of CVE-2025-55182 by sophisticated threat actors underscores the need for continuous defense.
Cloudflare remains committed to continuous surveillance for emerging exploit variants and refinement of WAF rules to detect evasive techniques. However, network-level protection is not a substitute for remediation at the source. Organizations must prioritize immediate patching of all affected React and Next.js assets. This combination of platform-level WAF defense and immediate application patching remains the only reliable strategy against this critical threat.
Indicators of Compromise
Tool/Scanner
User Agent String
Observation/Purpose
Nuclei
Nuclei – CVE-2025-55182
User-Agent for rapid, template-based scanning for React2Shell vulnerability
React2ShellScanner
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 React2ShellScanner/1.0.0
User-Agent for a likely custom React2Shell vulnerability scanner
Cloudflare has deployed a new protection to address a vulnerability in React Server Components (RSC). All Cloudflare customers are automatically protected, including those on free and paid plans, as long as their React application traffic is proxied through the Cloudflare Web Application Firewall (WAF).
Cloudflare Workers are inherently immune to this exploit. React-based applications and frameworks deployed on Workers are not affected by this vulnerability.
We strongly recommend that customers immediately update their systems to the most recent version of React, despite our WAF being designed to detect and prevent this exploit.
What you need to know
Cloudflare has been alerted by its security partners to a Remote Code Execution (RCE) vulnerability impacting Next.js, React Router, and other React frameworks (security advisory CVE-2025-55182, rated CVSS 10.0). Specifically, React version 19.0, 19.1, and 19.2, and Next.js from version 15 through 16 were found to insecurely deserialize malicious requests, leading to RCE.
In response, Cloudflare has deployed new rules across its network, with the default action set to Block. These new protections are included in both the Cloudflare Free Managed Ruleset (available to all Free customers) and the standard Cloudflare Managed Ruleset (available to all paying customers). More information about the different rulesets can be found in our documentation.
The rule ID is as follows:
Ruleset
Rule ID
Default action
Managed Ruleset
33aa8a8a948b48b28d40450c5fb92fba
Block
Free Ruleset
2b5d06e34a814a889bee9a0699702280
Block
Customers on Professional, Business, or Enterprise plans should ensure that Managed Rules are enabled — follow these steps to turn it on. Customers on a Free plan have these rules enabled by default.
We recommend that customers update to the latest version of React 19.2.1 and the latest versions of Next.js (16.0.7, 15.5.7, 15.4.8).
The rules were deployed at 5:00 PM GMT on Tuesday, December 2, 2025. Since their release until the publication of this blog and the official CVE announcement, we have not observed any attempted exploit.
Looking forward
The Cloudflare security team has collaborated with partners to identify various attack patterns and ensure the new rules effectively prevent any bypasses. Over the coming hours and days, the team will maintain continuous monitoring for potential attack variations, updating our protections as necessary to secure all traffic proxied via Cloudflare.
Kendra Albert gave an excellent talk at USENIX Security this year, pointing out that the legal agreements surrounding vulnerability disclosure muzzle researchers while allowing companies to not fix the vulnerabilities—exactly the opposite of what the responsible disclosure movement of the early 2000s was supposed to prevent. This is the talk.
Thirty years ago, a debate raged over whether vulnerability disclosure was good for computer security. On one side, full disclosure advocates argued that software bugs weren’t getting fixed and wouldn’t get fixed if companies that made insecure software wasn’t called out publicly. On the other side, companies argued that full disclosure led to exploitation of unpatched vulnerabilities, especially if they were hard to fix. After blog posts, public debates, and countless mailing list flame wars, there emerged a compromise solution: coordinated vulnerability disclosure, where vulnerabilities were disclosed after a period of confidentiality where vendors can attempt to fix things. Although full disclosure fell out of fashion, disclosure won and security through obscurity lost. We’ve lived happily ever after since.
Or have we? The move towards paid bug bounties and the rise of platforms that manage bug bounty programs for security teams has changed the reality of disclosure significantly. In certain cases, these programs require agreement to contractual restrictions. Under the status quo, that means that software companies sometimes funnel vulnerabilities into bug bounty management platforms and then condition submission on confidentiality agreements that can prohibit researchers from ever sharing their findings.
In this talk, I’ll explain how confidentiality requirements for managed bug bounty programs restrict the ability of those who attempt to report vulnerabilities to share their findings publicly, compromising the bargain at the center of the CVD process. I’ll discuss what contract law can tell us about how and when these restrictions are enforceable, and more importantly, when they aren’t, providing advice to hackers around how to understand their legal rights when submitting. Finally, I’ll call upon platforms and companies to adapt their practices to be more in line with the original bargain of coordinated vulnerability disclosure, including by banning agreements that require non-disclosure.
And this is me from 2007, talking about “responsible disclosure”:
This was a good idea—and these days it’s normal procedure—but one that was possible only because full disclosure was the norm. And it remains a good idea only as long as full disclosure is the threat.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.