Getting started with new Amazon RDS for Db2

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/getting-started-with-new-amazon-rds-for-db2/

I am pleased to announce that IBM and AWS have come together to offer Amazon Relational Database Service (Amazon RDS) for Db2, a fully managed Db2 database engine running on AWS infrastructure.

IBM Db2 is an enterprise-grade relational database management system (RDBMS) developed by IBM. It offers a comprehensive set of features, including strong data processing capabilities, robust security mechanisms, scalability, and support for diverse data types. Db2 is a well-established choice among organizations for effectively managing data in various applications and handling data-intensive workloads due to its reliability and performance. Db2 has its roots in the pioneering work around data storage and structured query language (SQL) IBM has done since the 1970s. It has been commercially available since 1983, initially just for mainframes, and was later ported to Linux, Unix, and Windows platforms (LUW). Today, Db2 powers thousands of business-critical applications in all verticals.

With Amazon RDS for Db2, you can now create a Db2 database with just a few clicks in the AWS Management Console, one command to type with the AWS Command Line Interface (AWS CLI), or a few lines of code with the AWS SDKs. AWS takes care of the infrastructure heavy lifting, freeing your time for higher-level tasks such as schema and query optimizations for your applications.

If you are new to Amazon RDS or coming from an on-premises Db2 background, let me quickly recap the benefits of Amazon RDS.

  • Amazon RDS offers the same Db2 database as the one you use on-premises today. Your existing applications will reconnect to RDS for Db2 without changing their code.
  • The database runs on a fully managed infrastructure. You don’t have to provision servers, install the packages, install patches, or maintain the infrastructure in an operational state.
  • The database is also fully managed. We take care of the installation, minor version upgrades, daily backup, scaling, and high availability.
  • The infrastructure can scale up and down as required. You can simply stop and then restart the database to change the underlying hardware and meet changing performance requirements or benefit from last-generation hardware.
  • Amazon RDS offers a choice of storage types designed to deliver fast, predictable, and consistent I/O performance. For new or unpredictable workloads, you can configure the system to automatically scale your storage.
  • Amazon RDS automatically takes care of your backups, and you can restore them to a new database with just a few clicks.
  • Amazon RDS helps to deploy highly available architectures. Amazon RDS synchronously replicates data to a standby database in a different Availability Zone (an Availability Zone is a group of distinct data centers). When a failure is detected with a Multi-AZ deployment, Amazon RDS automatically fails over to the standby instance and routes requests without changing the database endpoint DNS name. This switch happens with minimal downtime and zero data loss.
  • Amazon RDS is built on the secure infrastructure of AWS. It encrypts data in transit using TLS and at rest using keys managed with AWS Key Management Service (AWS KMS). This helps you deploy workloads that are compliant with your company or industry regulations, such as FedRAMP, GDPR, HIPAA, PCI, and SOC.
  • Third-party auditors assess the security and compliance of Amazon RDS as part of multiple AWS compliance programs and you can verify the full list of Amazon RDS compliance validations.

You can migrate your existing on-premises Db2 database to Amazon RDS using native Db2 tools, such as restore and import, or AWS Database Migration Service (AWS DMS). AWS DMS allows you to migrate databases in a single operation or continuously, while your applications continue to update the data on the source database, until you decide on the cut off.

Amazon RDS supports multiple tools for monitoring your database instances, including Amazon RDS Enhanced Monitoring and Amazon CloudWatch, or you can continue to use the IBM Data Management Console or IBM DSMtop.

Let’s see how it works
I always like to get my hands on a new service to learn how it works. Let’s create a Db2 database and connect to it using the standard tool provided by IBM. I assume most of you reading this post come from an IBM Db2 background and don’t know much about Amazon RDS.

First, I create a Db2 database. To do this, I navigate to the Amazon RDS page of the AWS Management Console and select Create database. For this demo, I’ll accept most of the default values. I’ll show you, however, all the sections and will comment on the important configuration points you have to think about.

I select Db2 from among the multiple database engines Amazon RDS offers.

RDS for Db2 - create DB - step 1I scroll down the page and select IBM Db2 Standard and Engine Version 11.5.9. Amazon RDS patches the database instances automatically if you so desire. You can learn more about Amazon RDS database maintenance here.

I select Production. Amazon RDS will deploy a default configuration tuned for high availability and fast, consistent performance.

RDS for Db2 - create DB - step 2

RDS for Db2 - create DB - multi-AZ deployment

Under Settings, I give a name to my RDS instance (this is not the Db2 catalog name!), and I select the master username and password.

Under Instance configuration, I choose the type of node to run my database. This will define the hardware characteristics of the virtual server: the number of vCPUs, quantity of memory, and so on. Depending on the requirements of your application, you can allocate instances offering up to 32 vCPUs and 128 GiB of RAM for IBM Db2 Standard instances. When you select IBM Db2 Advanced instances, you can allocate instances offering up to 128 vCPUs and 1 TiB of RAM. This parameter has a direct impact on the price.

RDS for Db2 - create DB - settings

RDS for Db2 - create DB - instance configuration

Under Storage, I choose the type of Amazon Elastic Block Store (Amazon EBS) volumes, their size, and their IOPS and throughput. For this demo, I accept the values proposed by default. This is also a set of parameters that directly impact the price.

RDS for Db2 - create DB - step 4

Under Connectivity, I select the VPC (in AWS terms, a VPC is a private network) where the database will be deployed. Under Public access, I select No to make sure the database instance is only accessible from my private network. I can’t think of a (good) use case where you want to select Yes for this option.

This is also where you select the VPC security group. A security group is a network filter that defines what IP addresses or networks can access your database instance and on what TCP port. Be sure to select or create a security group with TCP 50000 open to allow applications to connect to your Db2 database.

RDS for Db2 - create DB - step 5

I leave all other options with their default value. It is important to open the Additional configuration section at the very bottom of the page. This is where you can give an Initial database name. If you don’t name your Db2 database here, your only option will be to restore an existing Db2 database backup on that instance.

This section also contains the parameters for the Amazon RDS automatic backup. You can choose a time window and how long we will retain the backups.

I accept all the defaults and select Create database.

RDS for Db2 - create DB - step 6

After a few minutes, you can see your database is available.

I select the DNS name of the database instance Endpoint, and I connect to a Linux machine running in the same network. After installing the Db2 client package that I downloaded from the IBM website, I type the following commands to connect to the database. There is nothing specific to Amazon RDS here.

db2 catalog TCPIP node blognode remote awsnewsblog-demo.abcdef.us-east-2.rds-preview.amazonaws.com server 50000
db2 catalog database NEWSBLOG as blogdb2 at node blognode authentication server_encrypt
db2 connect to blogdb2 user admin using MySuperPassword

Once connected, I download a sample dataset and script from the popular Db2Tutorial website. I run the scripts against the database I just created.

wget https://www.db2tutorial.com/wp-content/uploads/2019/06/books.zip
unzip books.zip 
db2 -stvf ./create.sql 
db2 -stvf ./data.sql 
db2 "select count(*) author_count from authors"

RDS for Db2 - result of query

As you can see, there is nothing specific to Amazon RDS when it comes to connecting and using the database. I use standard Db2 tools and scripts.

One more thing
Amazon RDS for Db2 requires you to bring your own Db2 license. You must enter your IBM customer ID and site number before starting a Db2 instance.

To do so, create a custom DB parameter group and attach it to your database instance at launch time. A DB parameter group acts as a container for engine configuration values that are applied to one or more DB instances. In a Db2 parameter group, there are two parameters specific to IBM Db2 licenses: your IBM Customer Number (rds.ibm_customer_id) and your IBM site number (rds.ibm_site_id).

RDS for IBM Db2 - Parameter Group

If you do not know your site number, reach out to your IBM sales organization for a copy of a recent Proof-of-Entitlement (PoE), invoice, or sales order. All these documents should include your site number.

Pricing and availability
Amazon RDS for Db2 is available in all AWS Regions except China and GovCloud.

Amazon RDS pricing is on demand, and there are no upfront costs or subscriptions. You only pay by the hour when the database is running, plus the GB per month of database storage provisioned and backup storage you use and the number of IOPS you provision. The Amazon RDS for Db2 pricing page has the details of pricing per Region. As I mentioned earlier, Amazon RDS for Db2 requires you to bring your own Db2 license.

If you already know Amazon RDS, you’ll be delighted to have a new database engine available for your application developers. If you’re coming from an on-premises world, you will love the simplicity and automation that Amazon RDS offers.

You can learn many more details on the Amazon RDS for Db2 documentation page. Now go and deploy your first database with Amazon RDS for Db2 today!

— seb

Announcing throughput increase and dead letter queue redrive support for Amazon SQS FIFO queues

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/announcing-throughput-increase-and-dead-letter-queue-redrive-support-for-amazon-sqs-fifo-queues/

With Amazon Simple Queue Service (Amazon SQS), you can send, store, and receive messages between software components at any volume. Today, Amazon SQS has introduced two new capabilities for first-in, first-out (FIFO) queues:

  • Maximum throughput has been increased up to 70,000 transactions per second (TPS) per API action in selected AWS Regions, supporting sending or receiving up to 700,000 messages per second with batching.
  • Dead letter queue (DLQ) redrive support to handle messages that are not consumed after a specific number of retries in a way similar to what was already available for standard queues.

Let’s take a more in-depth look at how these work in practice.

FIFO queues throughput increase up to 70K TPS
FIFO queues are designed for applications that require messages to be processed exactly once and in the order in which they are sent. While standard queues have an unlimited throughput, FIFO queues have an upper quota in the number of TPS per API action.

Standard and FIFO queues support batch actions that can send and receive up to 10 messages with a single API call (up to a maximum total payload of 256 KB). This means that a FIFO queue can process up to 10 times more messages per second than its maximum throughput.

At launch in 2016, FIFO queues supported up to 300 TPS per API action (3,000 messages per second with batching). This was enough for many use cases, but some customers asked for more throughput.

With high throughput mode launched in 2021, FIFO queues introduced a tenfold increase of the maximum throughput and could process up to 3,000 TPS per API action, depending on the Region. One year later, that quota was doubled to up to 6,000 TPS per API action.

This year, Amazon SQS has already increased FIFO queue throughput quota two times, to up to 9,000 TPS per API action in August and up to 18,000 TPS per API action in October (depending on the Region).

Today, the Amazon SQS team has been able to increase the FIFO queue throughput quota again, allowing you to process up to 70,000 TPS per API action (up to 700,000 messages per second with batching) in the US East (N. Virginia), US West (Oregon), and Europe (Ireland) Regions. This is more than two hundred times the maximum throughput at launch.

DLQ redrive support for FIFO queues
With Amazon SQS, messages that are not consumed after a specific number of retries can automatically be moved to a DLQ. There, messages can be analyzed to understand the reason why they have not been processed correctly. Sometimes there is a bug or a misconfiguration in the consumer application. Other times the messages contain invalid data from the source applications that needs to be fixed to allow the messages to be processed again.

Either way, you can define a plan to reprocess these messages. For example, you can fix the consumer application and redrive all messages to the source queue. Or you can create a dedicated queue where a custom application receives the messages, fixes their content, and then sends them to the source queue.

To simplify moving the messages back to the source queue or to a different queue, Amazon SQS allows you to create a redrive task. Redrive tasks are already available for standard queues. Starting today, you can also start a redrive task for FIFO queues.

Using the Amazon SQS console, I create a first queue (my-dlq.fifo) to be used as a DLQ. To redrive messages back to the source FIFO queue, the queue type must match, so this is also a FIFO queue.

Then, I create a source FIFO queue (my-source-queue.fifo) to handle messages as usual. When I create the source queue, I configure the first queue (my-dlq.fifo) as the DLQ and specify 3 as the Maximum receives condition under which messages are moved from the source queue to the DLQ.

Console screenshot.

When a message has been received by a consumer for more than the number of times specified by this condition, Amazon SQS moves the message to the DLQ. The original message ID is retained and can be used to uniquely track the message.

To test this setup, I use the console to send a message to the source queue. Then, I use the AWS Command Line Interface (AWS CLI) to receive the message multiple times without deleting it.

aws sqs receive-message --queue-url https://sqs.eu-west-1.amazonaws.com/123412341234/my-source-queue.fifo
{
    "Messages": [
        {
            "MessageId": "ef2f1c72-4bfe-4093-a451-03fe2dbd4d0f",
            "ReceiptHandle": "...",
            "MD5OfBody": "0f445a578fbcb0c06ca8aeb90a36fcfb",
            "Body": "My important message."
        }
    ]
}

To receive the same message more than once, I wait for the time specified in the queue visibility timeout to pass (30 seconds by default).

After the third time, the message is not in the source queue because it has been moved to the DLQ. When I try to receive messages from the source queue, the list is empty.

aws sqs receive-message --queue-url https://sqs.eu-west-1.amazonaws.com/123412341234/my-source-queue.fifo
{
    "Messages": []
}

To confirm that the message has been moved, I poll the DLQ to see if the message is there.

aws sqs receive-message --queue-url https://sqs.eu-west-1.amazonaws.com/123412341234/my-dlq.fifo  
{
    "Messages": [
        {
            "MessageId": "ef2f1c72-4bfe-4093-a451-03fe2dbd4d0f",
            "ReceiptHandle": "...",
            "MD5OfBody": "0f445a578fbcb0c06ca8aeb90a36fcfb",
            "Body": "My important message."
        }
    ]
}

Now that the message is in the DLQ, I can investigate why the message has not been processed (well, I know the reason this time) and decide whether to redrive messages from the DLQ using the Amazon SQS console or the new redrive API that was introduced a few months ago. For this example, I use the console. Back on the Amazon SQS console, I select the DLQ queue and choose Start DLQ redrive.

In Redrive configuration, I choose to redrive the messages to the source queue. Optionally, I can specify another FIFO queue as a custom destination. I use System optimized in Velocity control settings to redrive messages with the maximum number of messages per second optimized by Amazon SQS. Optionally, if there is a large number of messages in the DLQ, I can configure a custom maximum rate of messages per second to avoid overloading consumers.

Console screenshot.

Before starting the redrive task, I can use the Inspect messages section to poll and check messages. I already decided what to do, so I choose DLQ redrive to start the task. I have only one message to process, so the redrive task completes very quickly.

Console screenshot.

As expected, the message is back in the source queue and is ready to be processed again.

Console screenshot.

Things to know
Dead letter queue (DLQ) support for FIFO queues is available today in all AWS Regions where Amazon SQS is offered with the exception of GovCloud Regions and those based in China.

In the DLQ configuration, the maximum number of receives should be between 1 and 1,000.

There is no additional cost for using high throughput mode or a DLQ. Every Amazon SQS action counts as a request. A single request can send or receive from 1 to 10 messages, up to a maximum total payload of 256 KB. You pay based on the number of requests, and requests are priced differently between standard and FIFO queues.

As part of the AWS Free Tier, there is no cost for the first million requests per month for standard queues and for the first million requests per month for FIFO queues. For more information, see Amazon SQS pricing.

With these updates and the increased throughput, you can cover the vast majority of use cases with FIFO queues.

Use Amazon SQS FIFO queues to have high throughput, exactly-once processing, and first-in-first-out delivery.

— Danilo

Amazon EBS Snapshots Archive is now available with AWS Backup

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/amazon-ebs-snapshots-archive-is-now-available-with-aws-backup/

Today we announce the availability of Amazon Elastic Block Store (Amazon EBS) Snapshots Archive with AWS Backup. Previously available only in the Amazon EC2 console or Amazon Data Lifecycle Manager, this feature gives you the ability to transition your infrequently accessed Amazon EBS Snapshots to low-cost archive, long-term storage of your rarely-accessed snapshots that do not need frequent or fast retrieval.

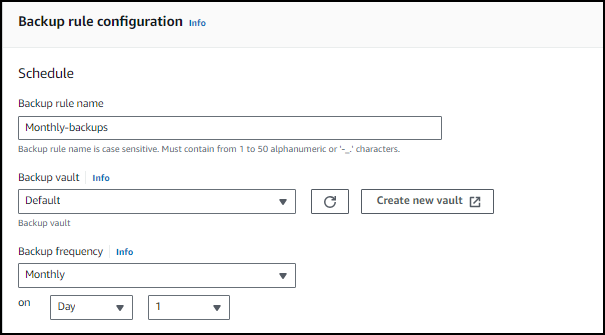
Amazon EBS Snapshots Archive in the AWS Backup console
Snapshots Archive with AWS Backup is only available for snapshots with a backup frequency of one month or longer (28-day cron expression) and a retention of more than 90 days. This is a protective measure to ensure that you don’t archive snapshots, such as hourly snapshots that wouldn’t benefit from the transition to the cold tier.

Backup frequency

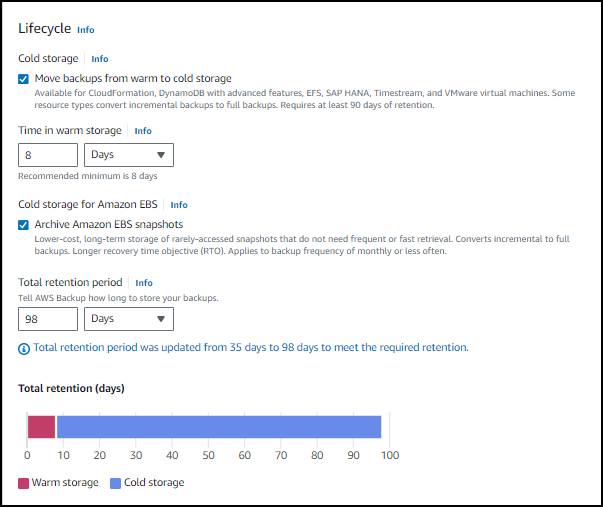
The ability to archive Amazon EBS Snapshots is a new parameter of the Lifecycle section of the AWS Backup Plans. You must explicitly opt into moving your Amazon EBS Snapshots to cold storage, because this has different properties of our existing cold storage including:

  1. Always converting an incremental backup to a full backup.
  2. Longer recovery time objective (RTO) (up to 72 hours).
  3. Limitations on the frequency of backups that can be transitioned to cold storage (monthly or greater).

Time in warm storage indicates how long the backups will remain in warm storage before they are transitioned to cold storage. Total retention period is the total time the backups will be retained by AWS Backup, and its value is the sum of both warm and cold storage. For backups in cold storage, the minimum retention period is 90 days. This is why the default total retention is 98 days (8 days in warm + 90 days in cold). The bar graph shows the total retention of your backups and where the backups will reside during that time. In the example shown in this graph, 8 days is in warm storage (red bar), and 90 days is in cold storage (blue bar).

Cold storage for Amazon EBS Snapshots

To restore or use the archived Amazon EBS snapshot today (outside of AWS Backup), you have to follow a two-step process:

  1. Temporarily or permanently restore the snapshot from archive to standard tier.
  2. Once it’s in standard tier, call the CreateVolume API from the standard tier.

With this announcement, using either the AWS Backup console or the API to restore the archived Amazon EBS snapshot in AWS Backup, the following restore workflow applies:

  1. Enter the number of days you want to temporarily restore your snapshot from cold to standard tier.
  2. Choose your volume configuration.

Restore archived EBS snapshot

The end result will be a restored EBS volume. You will not have to manually move the snapshot from cold to standard tier, then restore the volume, this will be done automatically for you.

Now available
Amazon EBS Snapshots Archive with AWS Backup is available for you today in all AWS Regions except China and AWS GovCloud (US).

As usual, you pay as you go, with no minimum or fixed fees. There are two metrics that influence Amazon EBS Snapshots Archive billing: data storage and data retrieval. You are charged for a 90-day period at minimum. This means that if you delete a snapshot archive or permanently restore it less than 90 days after creation, then we charge for the full 90-day period. The AWS Backup pricing page has the details.

– Veliswa

Replication failback and increased IOPS are new for Amazon EFS

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/replication-failback-and-increased-iops-are-new-for-amazon-efs/

Today, Amazon Elastic File System (Amazon EFS) has introduced two new capabilities:

  • Replication failback – Failback support for EFS replication makes it easier and more cost-effective to synchronize changes between EFS file systems when performing disaster recovery (DR) workflows. You can now quickly replicate incremental changes from your secondary back to your primary file system after disaster events and other DR-related activities.
  • Increased IOPS – Amazon EFS now supports up to 250,000 read IOPS and up to 50,000 write IOPS per file system, making it easier to run more IOPS-heavy workloads at any scale for virtual servers, containers, and serverless functions that require shared storage.

Let’s see more in depth how these work in practice.

Introducing Amazon EFS replication failback
With Amazon EFS replication, you can create a replica of your file system in the same or in another AWS Region. When replication is enabled, Amazon EFS automatically keeps the primary (source) and secondary (destination) file systems synchronized. To help you meet your compliance and business continuity goals, EFS replication is designed to provide a recovery point objective (RPO) and a recovery time objective (RTO) measured in minutes.

Now, with failback support, you can respond to disaster recovery (DR) events, conduct planned business continuity tests, and manage other DR-related activities with greater speed and cost efficiency. Failback support allows you to switch the direction of replication between the primary and secondary file systems. EFS replication keeps the two file systems in sync by copying only incremental changes, eliminating the need to make full copies of your data or use a self-managed, custom solution to complete a recovery workflow.

Using Amazon EFS replication failback
I have a file system replicated to another Region. As part of a periodic DR test, I want to switch to using the secondary file system and then revert back to the primary file system, preserving all the changes made on the secondary file system. To do so, I can use EFS Replication failback in just a few steps.

First, I delete the replication from the primary (source) to the secondary (destination) file system. After this, the secondary file system becomes writable. To do so, in the Amazon EFS console, I check I am in the correct Region and select the secondary file system. In the Replication tab, I choose Delete replication and confirm deletion. I can also start from the primary file system. In that case, the Delete replication link in the Replication tab opens a new browser tab and asks to confirm deletion like before.

I can now use the secondary file system and change its data as needed.

To go back to using the primary file system, I create a “reverse replication” from the secondary to the primary file system. To do so, I check I am in the correct Region and select the secondary file system. In the Replication tab, I choose Create replication and the new option Replicate to existing file system. Then, I select the Region of the primary file system and use the console to browse the EFS file systems in that Region and choose the primary one.

Console screenshot.

The console warns me that Replication overwrite protection is enabled for the primary file system. I follow the Disable protection link to open a new browser tab and edit the primary file system to disable replication overwrite protection.

Console screenshot.

Now, I go back to the browser tab where I am creating the failback replication from the secondary to the primary file system. I refresh the protection check and choose to create the replication.

Console screenshot.

In the following dialog, I confirm that I want Amazon EFS to write to the primary file system.

Console screenshot.

To know when the primary file system is back in sync, I check the Last synced timestamp in the Replication tab, which indicates that all changes made to the source file system before that time are replicated to the destination. Optionally, I can look at the TimeSinceLastSync metric (expressed in minutes) in Amazon CloudWatch to understand how data is being replicated.

Console screenshot.

When the primary file system is back in sync, I delete the replication from the secondary to the primary file system. To complete the restore of the original configuration, I again create the replication from the primary to the secondary file system.

Increased IOPS per file system
The Amazon EFS team has been able to increase IOPS again! The last time they did it was just a few months back. Starting today, an EFS file system can handle up to 50,000 write IOPS (a 2x improvement) and up to 250,000 read IOPS (a 4.5x improvement) when working with frequently-accessed data from a high-performance cache managed by Amazon EFS.

You can monitor the percentage utilization of your file system’s available IOPS using the PercentIOLimit CloudWatch metric. This metric considers the maximum IOPS for writes and uncached reads, including combinations of the two. Reads from the cache are not included in the PercentIOLimit metric.

With these performance improvements, you can run even more IOPS-demanding workloads on Amazon EFS, such as machine learning (ML) training, fine-tuning, and inference. Other use cases that can benefit from the increased IOPS are data science user shares, SaaS applications, and media processing.

Things to know
EFS replication failback is available in all AWS Regions where EFS is available. There are no additional costs for using replication failback. You pay for the usual replication and file system changes as described in Amazon EFS pricing.

The increased IOPS limits are immediately available for all file systems using the Elastic Throughput mode in all Regions where EFS is available. You don’t need to do anything to benefit from these performance improvements. To achieve the maximum IOPS, your application needs sufficient parallelization. For example, using multiple clients and distributing the load across a large number of files. For more information, see the performance tips in the user guide.

Learn more
Amazon EFS product page

— Danilo

AWS Control Tower adds new controls to help customers meet digital sovereignty requirements

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-control-tower-helps-customers-meet-digital-sovereignty-requirements/

Today, we added to AWS Control Tower a set of 65 purpose-built controls to help you meet your digital sovereignty requirements.

Digital sovereignty is the control of your digital assets: where the data resides, where it flows, and who has control over it. Since the creation of the AWS Cloud 17 years ago, we have been committed to giving you control over your data.

In November last year, we launched the AWS Digital Sovereignty Pledge, our commitment to offering all AWS customers the most advanced set of sovereignty controls and features available in the cloud. Since then, we have announced several steps in that direction. The AWS Nitro System has been validated by an independent third party to confirm that it contains no mechanism that allows anyone at AWS to access your data on AWS hosts. We launched AWS Dedicated Local Zones, a piece of infrastructure that is fully managed by AWS and built for exclusive use by a customer or community and placed in a customer-specified location or data center. And more recently, we announced the construction of a new independent sovereign Region in Europe.

The introduction of AWS Control Tower controls that support digital sovereignty is an additional step in our roadmap of capabilities for data residency, granular access restriction, encryption, and resilience.

AWS Control Tower offers a simple and efficient way to set up and govern a secure, multi-account AWS environment. It establishes a landing zone that is based on best-practices blueprints, and it enables governance using controls you can choose from a prepackaged list. The landing zone is a well-architected, multi-account baseline that follows AWS best practices. Controls implement governance rules for security, compliance, and operations.

The level of control required for digital assets greatly varies across industries and countries. Customers operating in highly regulated sectors might have the obligation to keep their data in a specific country or region, such as the European Union. Others might have obligations related to data encryption and where the encryption keys are kept, and so on. Furthermore, digital sovereignty requirements evolve rapidly, making it challenging to define and implement all the required controls. Many customers have told us they are concerned that they will have to choose between the full power of AWS and a feature-limited sovereign cloud solution that could hamper their ability to innovate, transform, and grow. We firmly believe that you shouldn’t have to make this choice.

AWS Control Tower helps reduce the time it takes to define, implement, and manage controls required to govern where your data is stored, transferred, and processed at scale.

AWS Control Tower offers you a consolidated view of the controls enabled, your compliance status, and controls evidence across your multiple accounts. This information is available on the console and by calling our APIs. As requirements and AWS services evolve, AWS Control Tower provides you with updated controls to help you continually manage your digital sovereignty needs.

Here are a couple of examples of the controls we added:

  • Operator access – Require that an Amazon Elastic Compute Cloud (Amazon EC2) dedicated host uses an AWS Nitro instance type.
  • Controlling access to your data – Require that an Amazon Elastic Block Store (Amazon EBS) snapshot cannot be publicly restorable.
  • Encryption at rest and in transit, including advanced key management strategies – Require an EC2 instance to use an AWS Nitro instance type that supports encryption in-transit between instances when created using the AWS::EC2::Instance resource type. It also requires that an Amazon Relational Database Service (Amazon RDS) database instance has encryption at rest configured to use an AWS KMS key that you specify for supported engine types.

These are just four examples from three categories. We’ve added 65 new controls, with over 245+ controls available under the digital sovereignty category grouping. The full list is available in the AWS Control Tower documentation.

One of the technical mechanisms AWS Control Tower uses to prevent accidental data storage or flow in a Region is the Region deny control. This parameter allows system administrators to deny access to AWS services and operations in selected AWS Regions. Until today, Region deny control could only be applied for an entire landing zone and all its organizational units (OUs) and accounts. With this launch, you can configure a new Region deny control at the organizational unit level and select the services and IAM principals to allow based on your unique business needs.

Let’s see how to get started
For this demo, let’s imagine that I want to restrict access to AWS services in a set of Regions.

I open the AWS Management Console and navigate to the AWS Control Tower page. On the left navigation pane, under Control Library , I select Categories > Groups > Digital Sovereignty.

Control Tower - Digital Sovereignty - 01

I can review the list of controls available.

Control Tower - Digital Sovereignty - 02

I locate and select the control I want to enable: Deny access to AWS based on the requested AWS Region for an organizational unit. There is a description of the control and a list of frameworks it applies to (NIST 800 and PCI DSS). I select Enable control.

Control Tower - Digital Sovereignty - 03

On the next page, I select the Organizational units (OU) for which I want to enable this control.

Control Tower - Digital Sovereignty - 04

I select the AWS Regions where I will allow access. All Regions left unchecked will have their access denied once the control is enforced.

Control Tower - Digital Sovereignty - 05

Then, I review the service control policy (SCP). It contains a Deny statement to prevent access to the services or APIs listed. Optionally, I can add NotActions. This is a list of exceptions. The services or APIs listed under NotActions are authorized. In this example, I deny everything excepted three APIs: sqs:SendMessage, ec2:StartInstances, and s3:GetObject.

Control Tower - Digital Sovereignty - 06

On the last page, I add a list of IAM principals (users or roles) that will be exempted from the control. This is an exception list. I also tag my control as usual with AWS resources.

Control Tower - Digital Sovereignty - 07

On the last screen (not shown here), I review all my parameters and select Enable control.

I can verify the list of OU for which the control is enabled under the OUs enabled tab.

Control Tower - Digital Sovereignty - 08

The summary page shows all Regions, APIs, and IAM principals enabled for this OU. All the rest is denied. I can update the parameters at any time.

Control Tower - Digital Sovereignty - 09

Pricing and availability
AWS Control Tower is available in all commercial Regions and in US GovCloud.

There is no additional charge to use AWS Control Tower. However, when you set up AWS Control Tower, you will begin to incur costs for AWS services configured to set up your landing zone and mandatory controls.

Certain AWS services, such as Organizations and AWS IAM Identity Center, come at no additional charge. However, you will pay for services such as AWS Service Catalog, AWS CloudTrail, AWS Config, Amazon CloudWatch, Amazon Simple Notification Service (Amazon SNS), Amazon Simple Storage Service (Amazon S3), and Amazon Virtual Private Cloud (Amazon VPC) based on your usage of these services. You only pay for what you use, as you use it. The AWS Control Tower pricing page has the details.

The new AWS Control Tower controls alleviate the burden of identifying and deploying safeguards to meet your digital sovereignty requirements. This set of controls is fully managed, and we will update them as AWS services and digital sovereignty requirements evolve over time.

Go and configure the AWS Control Tower controls that help support your digital sovereignty requirements today.

— seb

Announcing new diagnostic tools for AWS Partner-Led Support (PLS) participants

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/announcing-new-diagnostic-tools-for-aws-partner-led-support-pls-participants/

We have added a set of diagnostic tools that will give participants in the AWS Partner-Led Support program access to diagnostic tools that will empower them to do an even better job of supporting their customers.

Intro to AWS Partner-Led Support
This AWS Partner Network (APN) program enables AWS Partners to act as the customer’s sole point of contact for technical support. Customers contact their support partner for technical assistance instead of directly contacting AWS. In many cases the partner can resolve the issue directly. If the partner cannot do this, they get guidance from AWS via their AWS Support plan.

Diagnostic tools
These are the same tools that AWS Support Engineers use to assist AWS customers.

When a customer contacts their partner for support, the partner will federate into the customer’s AWS account. Then they will use the new diagnostic tools to access the customer metadata that will help them to identify and diagnose the issue.

The tools are enabled by a set of IAM roles set up by the customer. The tools can access and organize metadata and CloudWatch metrics, but they cannot access customer data and they cannot make any changes to any of the customer’s AWS resources. Here is a small sample of the types of information that partners will be able to access:

  • EC2 Capacity Reservations
  • Lambda Functions List
  • GuardDuty Findings
  • Load Balancer Responses
  • RDS and Redshift Clusters

Each tool operates on a list of regions selected when the tool is run, all invocations of each tool are logged and are easily accessible for review, and the output from each invocation can be directed to one of several different regions.

The tools can be invoked from the AWS Management Console, with API access available in order to support in-house tools, automation, and integration.

Learn more

The service is available today for partners that have joined the Partner-Led Support program. For more information, see the AWS Partner Led Support page.

If you are a current AWS Partner and would like to learn more about this program with an eye toward qualifying and participating, please visit AWS Partner Central.

Learn more about AWS Diagnostic Tools here.

— Jeff;

Manage EDI at scale with new AWS B2B Data Interchange

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/introducing-aws-b2b-data-interchange-simplified-connections-with-your-trading-partners/

Today we’re launching AWS B2B Data Interchange, a fully managed service allowing organizations to automate and monitor the transformation of EDI-based business-critical transactions at cloud scale. With this launch, AWS brings automation, monitoring, elasticity, and pay-as-you-go pricing to the world of B2B document exchange.

Electronic data interchange (EDI) is the electronic exchange of business documents in a standard electronic format between business partners. While email is also an electronic approach, the documents exchanged via email must still be handled by people rather than computer systems. Having people involved slows down the processing of the documents and also introduces errors. Instead, EDI documents can flow straight through to the appropriate application on the receiver’s system, and processing can begin immediately. Electronic documents exchanged between computer systems help businesses reduce cost, accelerate transactional workflows, reduce errors, and improve relationships with business partners.

Work on EDI started in the 1970s. I remember reading a thesis about EDIFACT, a set of standards defining the structure of business documents, back in 1994. But despite being a more than 50-year-old technology, traditional self-managed EDI solutions deployed to parse, validate, map, and translate data from business applications to EDI data formats are difficult to scale as the volume of business changes. They typically do not provide much operational visibility into communication and content errors. These challenges often oblige businesses to fall back to error-prone email document exchanges, leading to high manual work, increased difficulty controlling compliance, and ultimately constraining growth and agility.

AWS B2B Data Interchange is a fully managed, easy-to-use, and cost-effective service for accelerating your data transformations and integrations. It eliminates the heavy lifting of establishing connections with your business partners and mapping the documents to your system’s data-formats and gives visibility on documents that can’t be processed.

It provides a low-code interface for business partner onboarding and EDI data transformation to easily import the processed data to your business applications and analytics solutions. B2B Data Interchange gives you easy access to monitoring data, allowing you to build dashboards to monitor the volume of documents exchanged and the status of each document transformation. For example, it is easy to create alarms when incorrectly formatted documents can’t be transformed or imported into your business applications.

It is common for large enterprises to have thousands of business partners and hundreds of types of documents exchanged with each partner, leading to millions of combinations to manage. AWS B2B Data Interchange is not only available through the AWS Management Console, it is also accessible with the AWS Command Line Interface (AWS CLI) and AWS SDKs. This allows you to write applications or scripts to onboard new business partners and their specific data transformations and to programmatically add alarms and monitoring logic to new or existing dashboards.

B2B Data Interchange supports the X12 EDI data format. It makes it easier to validate and transform EDI documents to the formats expected by your business applications, such as JSON or XML. The raw documents and the transformed JSON or XML files are stored on Amazon Simple Storage Service (Amazon S3). This allows you to build event-driven applications for real-time business data processing or to integrate business documents with your existing analytics or AI/ML solutions.

For example, when you receive a new EDI business document, you can trigger additional routing, processing, and transformation logic using AWS Step Functions or Amazon EventBridge. When an error is detected in an incoming document, you can configure the sending of alarm messages by email or SMS or trigger an API call or additional processing logic using AWS Lambda.

Let’s see how it works
As usual on this blog, let me show you how it works. Let’s imagine I am in charge of the supply chain for a large retail company, and I have hundreds of business partners to exchange documents such as bills of lading, customs documents, advanced shipment notices, invoices, or receiving advice certificates.

In this demo, I use the AWS Management Console to onboard a new business partner. By onboarding, I mean defining the contact details of the business partner, the type of documents I will exchange with them, the technical data transformation to the JSON formats expected by my existing business apps, and where to receive the documents.

With this launch, the configuration of the transport mechanism for the EDI document is managed outside B2B Data Interchange. Typically, you will configure a transfer gateway and propose that your business partner transfer the document using SFTP or AS2.

There are no servers to manage or application packages to install and configure. I can get started in just four steps.

First, I create a profile for my business partner.

B2B Data Interchange - Create profile

Second, I create a transformer. A transformer defines the source document format and the mapping to my existing business application data format: JSON or XML. I can use the graphical editor to validate a sample document and see the result of the transformation directly from the console. We use the standard JSONATA query and transformation language to define the transformation logic to JSON documents and standard XSLT when transforming to XML documents.

B2B Data Interchange - Create transformer - input

B2B Data Interchange - Create transformer - transformation

I activate the transformer once created.

B2B Data Interchange - Create transformer - activate

Third, I create a trading capability. This defines which Amazon Simple Storage Service (Amazon S3) buckets will receive the documents from a specific business partner and where the transformed data will be stored.

There is a one-time additional configuration to make sure proper permissions are defined on the S3 bucket policy. I select Copy policy and navigate to the Amazon S3 page of the console to apply the policies to the S3 bucket. One policy allows B2B Data Interchange to read from the incoming bucket, and one policy allows it to write to your outgoing bucket.

B2B Data Interchange - Create capability

B2B Data Interchange - Create capability - configure directory

While I am configuring the S3 bucket, it is also important to turn on Amazon EventBridge on the S3 bucket. This is the mechanism we use to trigger the data transformation upon the arrival of a new business document.

B2B Data Interchange - Enbale EventBridge on S3 bucket

Finally, back at the B2B Data Interchange configuration, I create a partnership. Partnerships are dedicated resources that establish a relationship between you and your individual trading partners. Partnerships contain details about a specific trading partner, the types of EDI documents you receive from them, and how those documents should be transformed into custom JSON or XML formats. A partnership links the business profile I created in the first step with one or multiple document types and transformations I defined in step two.

B2B Data Interchange - Create partnership

This is also where I can monitor the status of the last set of documents I received and the status of their transformation. For more historical data, you can navigate to Amazon CloudWatch using the links provided in the console.

B2B Data Interchange - Log group

To test my setup, I upload an EDI 214 document to the incoming bucket and a few seconds later, I can see the transformed JSON document appearing in the destination bucket.

B2B Data Interchange - Transformed document on the bucket

I can observe the status of document processing and transformation using Invocations and TriggeredRules CloudWatch metrics from EventBridge. From there, together with the CloudWatch Logs, I can build dashboards and configure alarms as usual. I can also configure additional enrichment, routing, and processing of the incoming or transformed business documents by writing an AWS Lambda function or a workflow using AWS Step Functions.

Pricing and availability
AWS B2B Data Interchange is available today in three of the AWS Regions: US East (Ohio, N. Virginia) and US West (Oregon).

There is no one-time setup fee or recurring monthly subscription. AWS charges you on demand based on your real usage. There is a price per partnership per month and a price per document transformed. The B2B Data Interchange pricing page has the details.

AWS B2B Data Interchange makes it easy to manage your trading partner relationships so you can automatically exchange, transform, and monitor EDI workflows at cloud scale. It doesn’t require you to install or manage any infrastructure and makes it easy for you to integrate with your existing business applications and systems. You can use the AWS B2B Data Interchange API or the AWS SDK to automate the onboarding of your partners. Combined with a fully managed and scalable infrastructure, AWS B2B Data Interchange helps your business to be more agile and scale your operations.

Learn more:

Go build!

— seb

Automatic restore testing and validation now available in AWS Backup

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/automatic-restore-testing-and-validation-is-now-available-in-aws-backup/

Performing automatic game day testing of all your critical resources is an important step in determining that you are prepared to respond to ransomware or any data loss event. This gives you the opportunity to take appropriate corrective actions based on the results and monitor results such as success or failure from these tests. Ultimately, you will be able to ascertain if the restore times meet your expected organization’s recovery time objective (RTO) goals, helping you develop improved recovery strategies.

Today, we’re announcing restore testing, a new capability in AWS Backup that allows you to perform restore testing of your AWS resources across storage, compute, and databases. With this feature, you can automate the entire restore testing process and avoid surprises later by determining now whether you can successfully recover using your backups in the event of a data loss such as ransomware. As an additional option, to demonstrate compliance with your organizational and regulatory data governance requirements, you can use the restore job results.

How it works
Restore testing in AWS Backup supports restore testing of resources for which the recovery points are created by AWS Backup, and the following services are supported: Amazon Elastic Block Store (Amazon EBS), Amazon Elastic Compute Cloud (Amazon EC2), Amazon Aurora, Amazon Relational Database Service (Amazon RDS), Amazon Elastic File Store (Amazon EFS), Amazon Simple Storage Service (Amazon S3), Amazon DynamoDB, Amazon FSx, Amazon DocumentDB, and Amazon Neptune. You can get started with restore testing from the AWS Backup console, AWS CLI, or AWS SDK.

Earlier, I created EC2 instances and a backup of these instances. Then, I created my restore testing plan in the AWS Backup console.

Create restore testing plan

In this General section, I enter the name of the plan, a test frequency, a Start time, and a Start within. Start time sets the time for the test to begin, for example, if you have a daily test frequency set, you specify what time the plan will run each day. Start within is the period of time in which the restore test is designated to begin. AWS Backup makes a best effort to commence all designated restore jobs during the Start within time window. You have a choice to keep this very minimal or very large based on your preference.

Figure 2: Section 1 Create restore testing plan

In the Recovery point selection section, I specify the vaults that the recovery points should come from, and a timeframe of eligible recovery points as part of this restore testing plan. I left the criteria for a recovery point at the default selection. I also didn’t opt to include recovery points generated by point-in-time recovery (PITR) in this restore testing plan.

section2_create

Tagging is optional so for the purposes of this test I didn’t add a tag. I was then finished with setup, and it was time for me to choose Create restore testing plan to proceed with creating this restore testing plan.

Figure 4: Finalize creation of restore testing plan

Once the restore testing plan has been created, it is time to assign resources. I start by specifying the IAM role that AWS Backup will assume when running the restore test. In terms of retention period before cleanup, I kept the default selection of deleting the restored resources immediately, to optimize costs. Alternatively, by specifying a retention period I could have also configured to integrate my own tests (for example, AWS Lambda) using Amazon EventBridge (CloudWatch Events) and send back validation status using the new PutRestoreValidationResult API so that it is reported in the restore job.

add_resource1

I have EC2 instances that I created and backed up earlier, and I specify that this plan is for Amazon EC2 resource types. I include all protected resources of this EC2 resource type in the selection scope. I have very few resources, so I didn’t add the optional tags.

add_resource2

I opted to use the default instance type for the restore. I also didn’t specify any additional parameters. It’s then time to choose Assign resources.

add_resource3

Once the resources have been assigned, all information related to the restore testing plan will be presented in a summarized form where you’ll be able to see when the restore testing jobs have executed.

Once I have enough restores performed over time, I can also view the Restore time history for every resource restored from the Protected resources tab.

Now available
Restore testing in AWS Backup is available in all AWS Regions where AWS Backup is available except AWS China Regions, AWS GovCloud (US), and Israel (Tel Aviv).
To learn more, visit the AWS Backup user guide. You can submit your questions to AWS re:Post for AWS Backup or through your usual AWS Support contacts.

— Veliswa

Use IAM Identity Center APIs to audit and manage application assignments

Post Syndicated from Laura Reith original https://aws.amazon.com/blogs/security/use-iam-identity-center-apis-to-audit-and-manage-application-assignments/

You can now use AWS IAM Identity Center application assignment APIs to programmatically manage and audit user and group access to AWS managed applications. Previously, you had to use the IAM Identity Center console to manually assign users and groups to an application. Now, you can automate this task so that you scale more effectively as your organization grows.

In this post, we will show you how to use IAM Identity Center APIs to programmatically manage and audit user and group access to applications. The procedures that we share apply to both organization instances and account instances of IAM Identity Center.

Automate management of user and group assignment to applications

IAM Identity Center is where you create, or connect, your workforce users one time and centrally manage their access to multiple AWS accounts and applications. You configure AWS managed applications to work with IAM Identity Center directly from within the relevant application console, and then manage which users or groups need permissions to the application.

You can already use the account assignment APIs to automate multi-account access and audit access assigned to your users using IAM Identity Center permission sets. Today, we expanded this capability with the new application assignment APIs. You can use these new APIs to programmatically control application assignments and develop automated workflows for auditing them.

AWS managed applications access user and group information directly from IAM Identity Center. One example of an AWS managed application is Amazon Redshift. When you configure Amazon Redshift as an AWS managed application with IAM Identity Center, and a user from your organization accesses the database, their group memberships defined in IAM Identity Center can map to Amazon Redshift database roles that grant them specific permissions. This makes it simpler for you to manage users because you don’t have to set database-object permissions for each individual. For more information, see The benefits of Redshift integration with AWS IAM Identity Center.

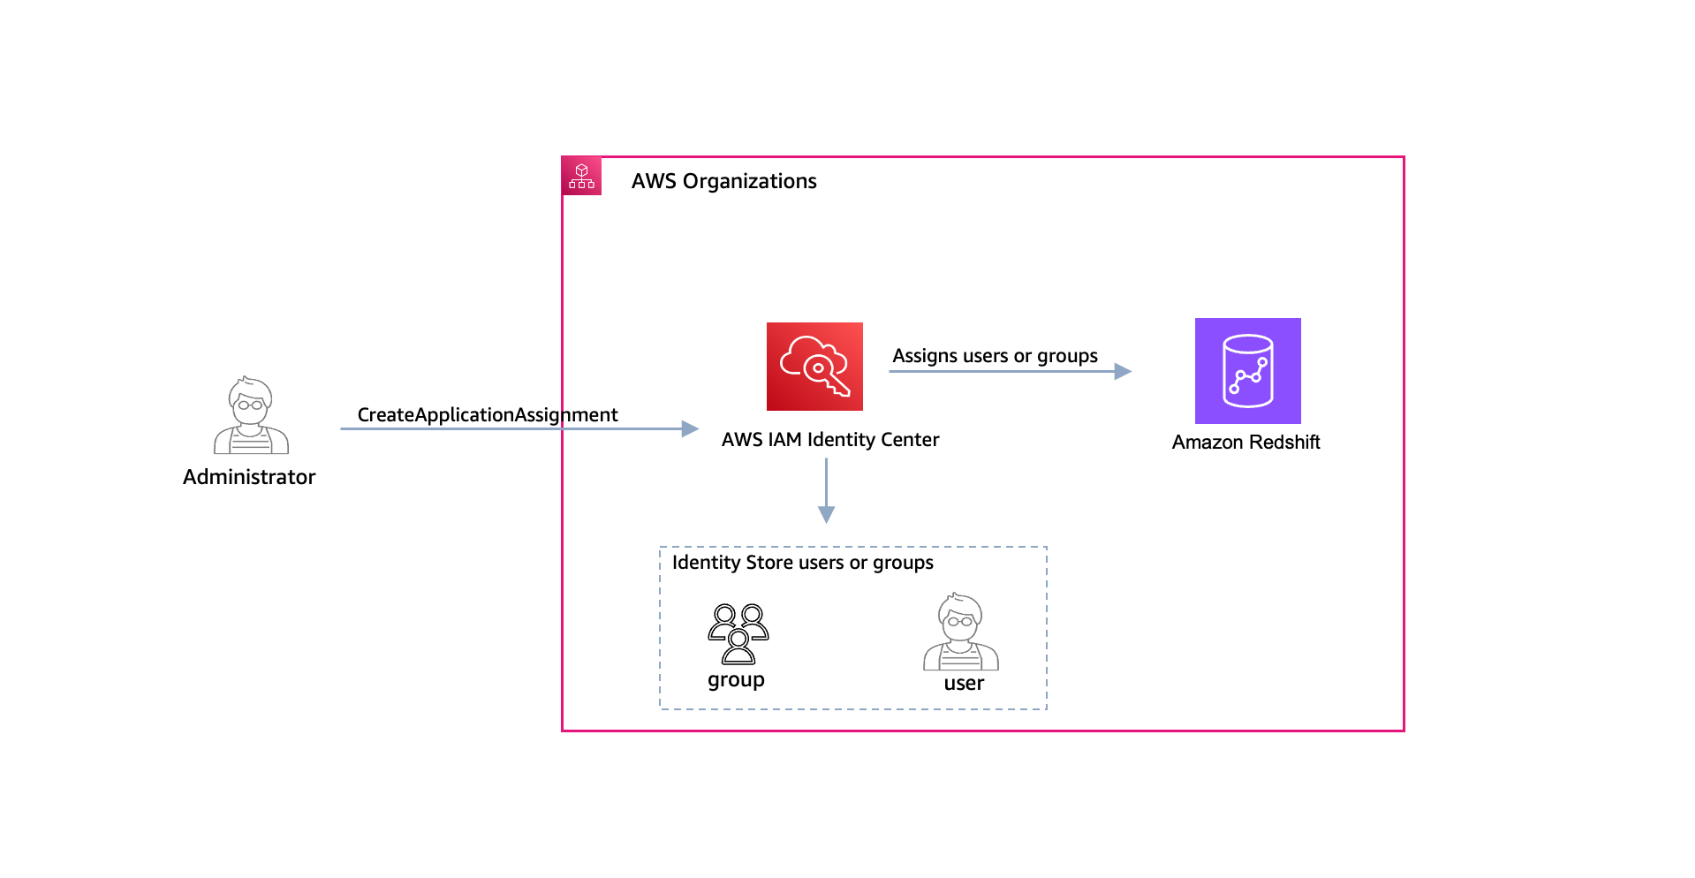
After you configure the integration between IAM Identity Center and Amazon Redshift, you can automate the assignment or removal of users and groups by using the DeleteApplicationAssignment and CreateApplicationAssignment APIs, as shown in Figure 1.

Figure 1: Use the CreateApplicationAssignment API to assign users and groups to Amazon Redshift

Figure 1: Use the CreateApplicationAssignment API to assign users and groups to Amazon Redshift

In this section, you will learn how to use Identity Center APIs to assign a group to your Amazon Redshift application. You will also learn how to delete the group assignment.

Prerequisites

To follow along with this walkthrough, make sure that you’ve completed the following prerequisites:

  • Enable IAM Identity Center, and use the Identity Store to manage your identity data. If you use an external identity provider, then you should handle the user creation and deletion processes in those systems.
  • Configure Amazon Redshift to use IAM Identity Center as its identity source. When you configure Amazon Redshift to use IAM Identity Center as its identity source, the application requires explicit assignment by default. This means that you must explicitly assign users to the application in the Identity Center console or APIs.
  • Install and configure AWS Command Line Interface (AWS CLI) version 2. For this example, you will use AWS CLI v2 to call the IAM Identity Center application assignment APIs. For more information, see Installing the AWS CLI and Configuring the AWS CLI.

Step 1: Get your Identity Center instance information

The first step is to run the following command to get the Amazon Resource Name (ARN) and Identity Store ID for the instance that you’re working with:

aws sso-admin list-instances

The output should look similar to the following:

{
  "Instances": [
      {
          "InstanceArn": "arn:aws:sso:::instance/ssoins-****************",
          "IdentityStoreId": "d-**********",
          "OwnerAccountId": "************",
          "Name": "MyInstanceName",
          "CreatedDate": "2023-10-08T16:45:19.839000-04:00",
          "State": {
              "Name": "ACTIVE"
          },
          "Status": "ACTIVE"
      }
  ],
  "NextToken": <<TOKEN>>
}

Take note of the IdentityStoreId and the InstanceArn — you will use both in the following steps.

Step 2: Create user and group in your Identity Store

The next step is to create a user and group in your Identity Store.

Note: If you already have a group in your Identity Center instance, get its GroupId and then proceed to Step 3. To get your GroupId, run the following command:

aws identitystore get-group-id --identity-store-id “d-********” –alternate-identifier “GroupName” ,

Create a new user by using the IdentityStoreId that you noted in the previous step.

aws identitystore create-user --identity-store-id "d-**********" --user-name "MyUser" --emails Value="[email protected]",Type="Work",Primary=true —display-name "My User" —name FamilyName="User",GivenName="My" 

The output should look similar to the following:

{
    "UserId": "********-****-****-****-************",
    "IdentityStoreId": "d--********** "
}

Create a group in your Identity Store:

aws identitystore create-group --identity-store-id d-********** --display-name engineering

In the output, make note of the GroupId — you will need it later when you create the application assignment in Step 4:

{
    "GroupId": "********-****-****-****-************",
    "IdentityStoreId": "d-**********"
}

Run the following command to add the user to the group:

aws identitystore create-group-membership --identity-store-id d-********** --group-id ********-****-****-****-************ --member-id UserId=********-****-****-****-************

The result will look similar to the following:

{
    "MembershipId": "********-****-****-****-************",
    "IdentityStoreId": "d-**********"
}

Step 3: Get your Amazon Redshift application ARN instance

The next step is to determine the application ARN. To get the ARN, run the following command.

aws sso-admin list-applications --instance-arn "arn:aws:sso:::instance/ssoins-****************"

If you have more than one application in your environment, use the filter flag to specify the application account or the application provider. To learn more about the filter option, see the ListApplications API documentation.

In this case, we have only one application: Amazon Redshift. The response should look similar to the following. Take note of the ApplicationArn — you will need it in the next step.

{

    "ApplicationArn": "arn:aws:sso:::instance/ssoins-****************/apl-***************",
    "ApplicationProviderArn": "arn:aws:sso::aws:applicationProvider/Redshift",
    "Name": "Amazon Redshift",
    "InstanceArn": "arn:aws:sso:::instance/ssoins-****************",
    "Status": "DISABLED",
    "PortalOptions": {
        "Visible": true,
        "Visibility": "ENABLED",
        "SignInOptions": {
            "Origin": "IDENTITY_CENTER"
        }
    },
    "AssignmentConfig": {
        "AssignmentRequired": true
    },
    "Description": "Amazon Redshift",
    "CreatedDate": "2023-10-09T10:48:44.496000-07:00"
}

Step 4: Add your group to the Amazon Redshift application

Now you can add your new group to the Amazon Redshift application managed by IAM Identity Center. The principal-id is the GroupId that you created in Step 2.

aws sso-admin create-application-assignment --application-arn "arn:aws:sso:::instance/ssoins-****************/apl-***************" --principal-id "********-****-****-****-************" --principal-type "GROUP"

The group now has access to Amazon Redshift, but with the default permissions in Amazon Redshift. To grant access to databases, you can create roles that control the permissions available on a set of tables or views.

To create these roles in Amazon Redshift, you need to connect to your cluster and run SQL commands. To connect to your cluster, use one of the following options:

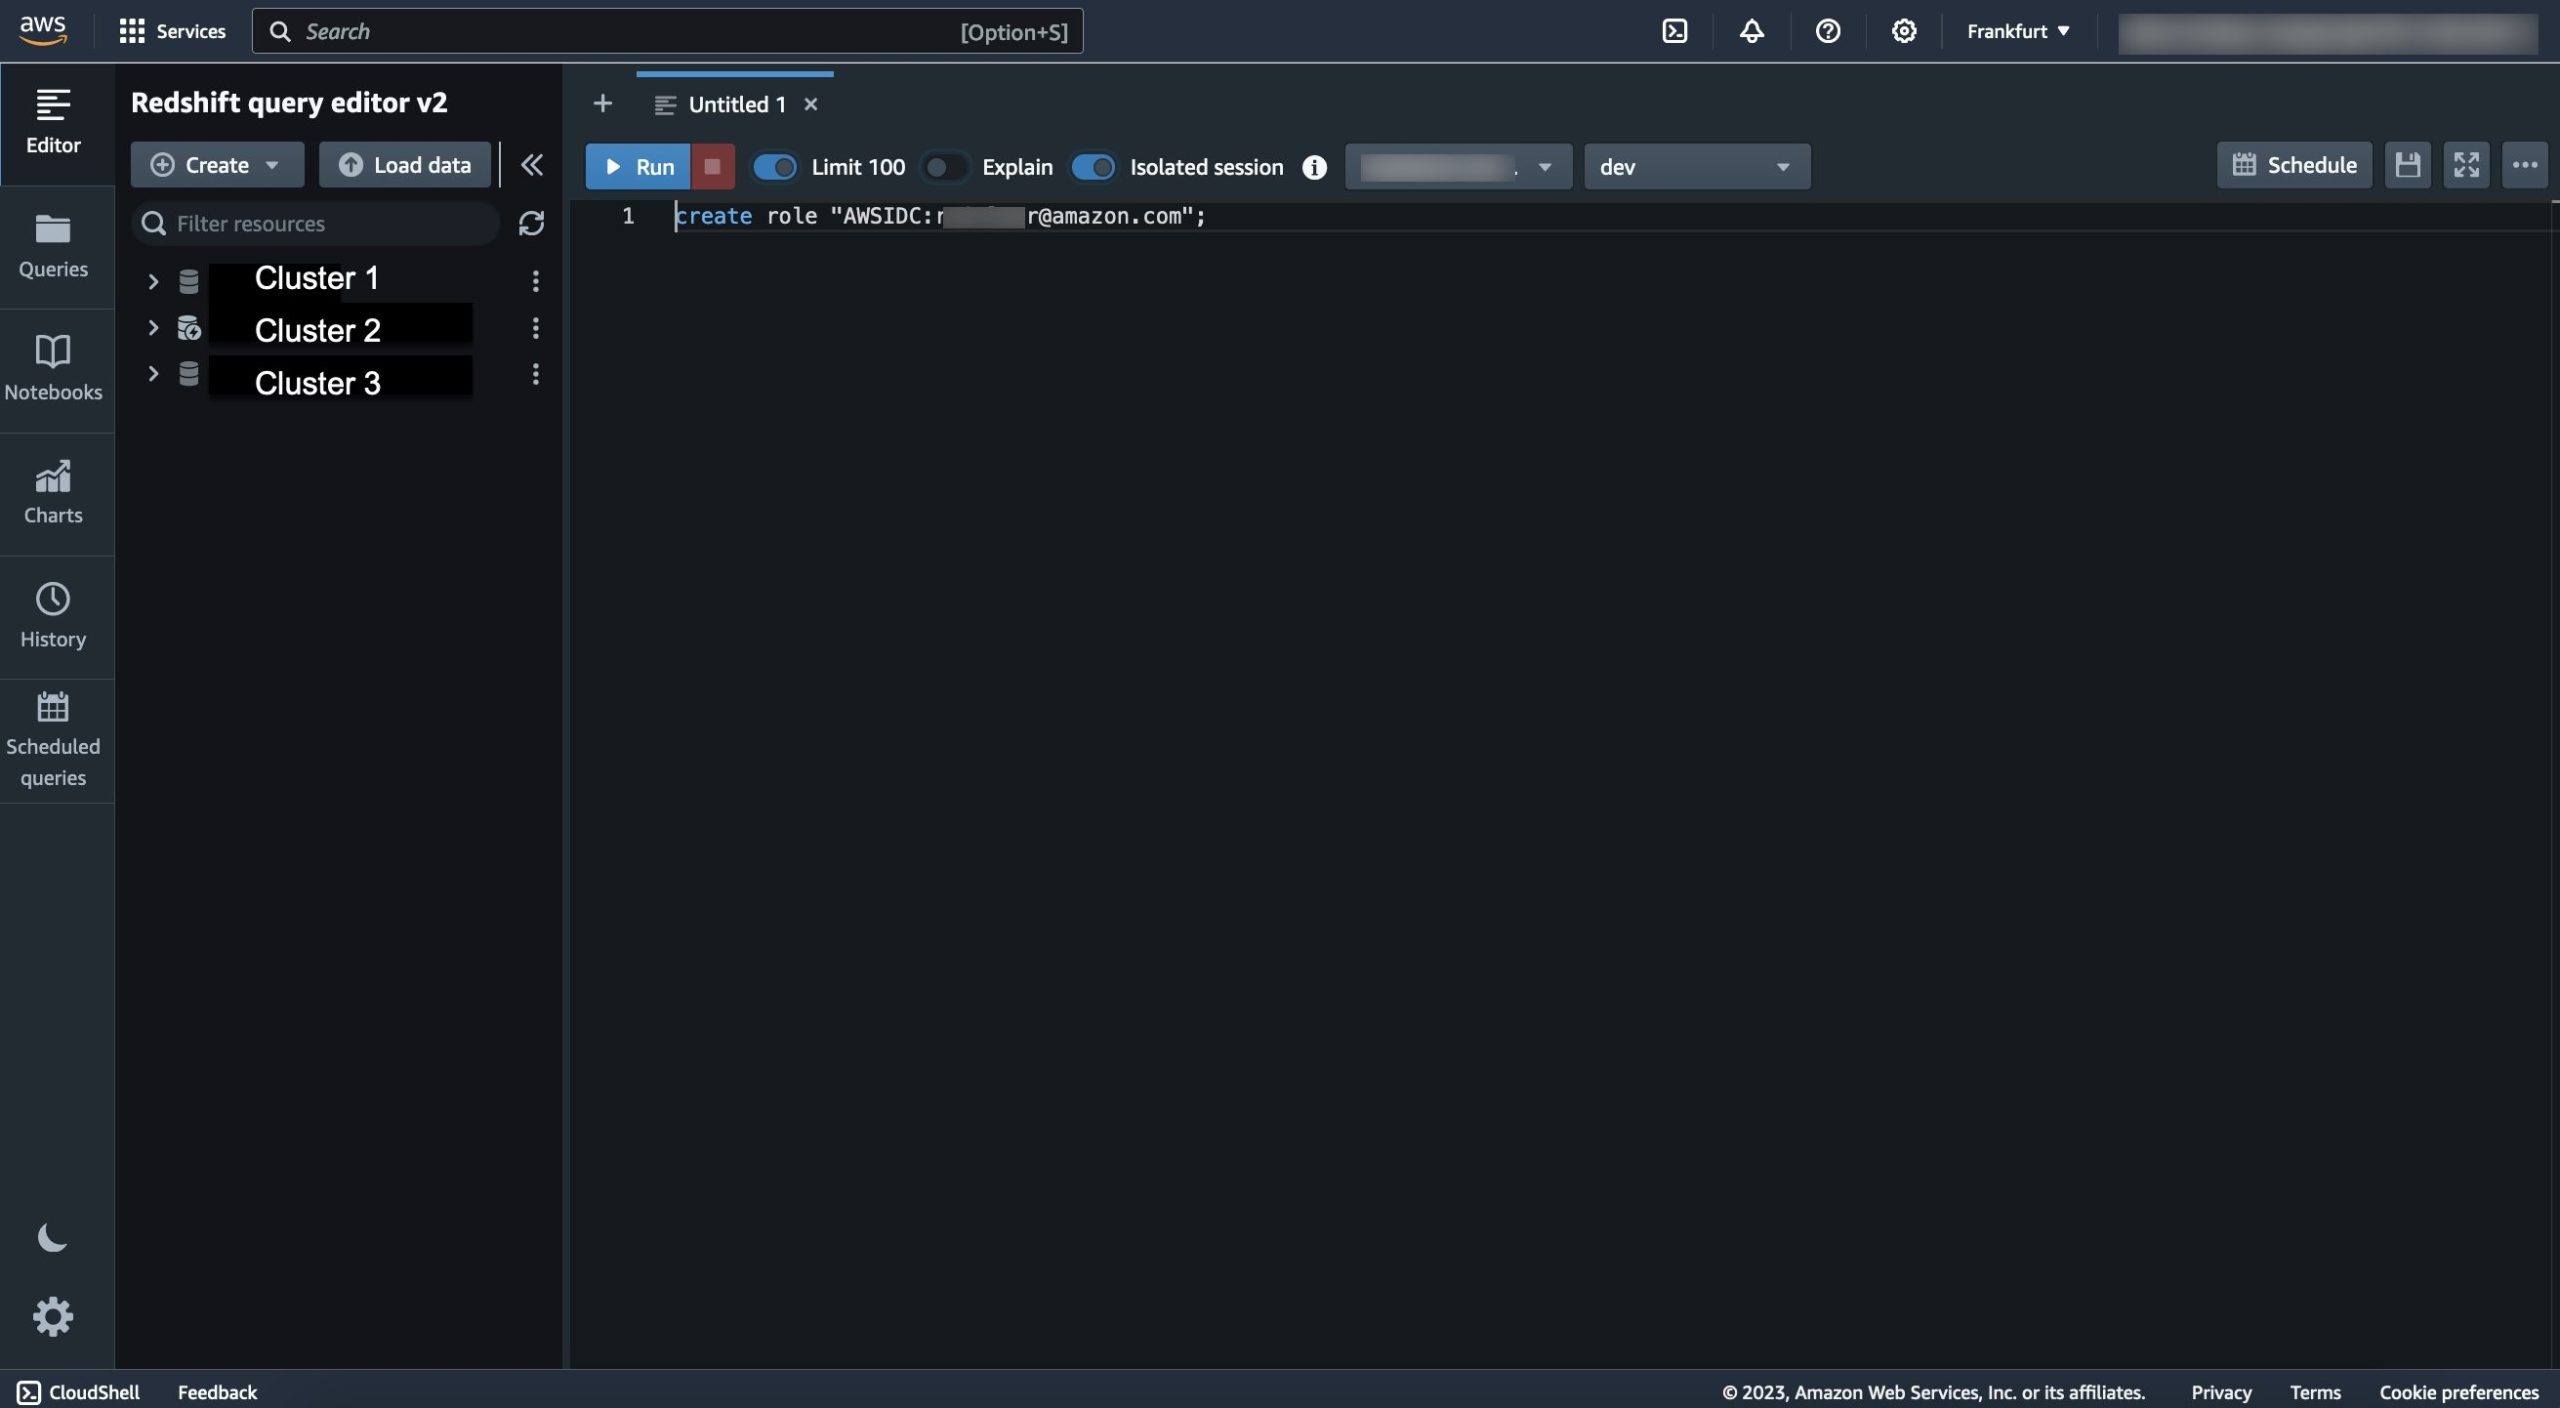
Figure 2 shows a connection to Amazon Redshift through the query editor v2.

Figure 2: Query editor v2

Figure 2: Query editor v2

By default, all users have CREATE and USAGE permissions on the PUBLIC schema of a database. To disallow users from creating objects in the PUBLIC schema of a database, use the REVOKE command to remove that permission. For more information, see Default database user permissions.

As the Amazon Redshift database administrator, you can create roles where the role name contains the identity provider namespace prefix and the group or user name. To do this, use the following syntax:

CREATE ROLE <identitycenternamespace:rolename>;

The rolename needs to match the group name in IAM Identity Center. Amazon Redshift automatically maps the IAM Identity Center group or user to the role created previously. To expand the permissions of a user, use the GRANT command.

The identityprovidernamespace is assigned when you create the integration between Amazon Redshift and IAM Identity Center. It represents your organization’s name and is added as a prefix to your IAM Identity Center managed users and roles in the Redshift database.

Your syntax should look like the following:

CREATE ROLE <AWSIdentityCenter:MyGroup>;

Step 5: Remove application assignment

If you decide that the new group no longer needs access to the Amazon Redshift application but should remain within the IAM Identity Center instance, run the following command:

aws sso-admin delete-application-assignment --application-arn "arn:aws:sso:::instance/ssoins-****************/apl-***************" --principal-id "********-****-****-****-************" --principal-type "GROUP"

Note: Removing an application assignment for a group doesn’t remove the group from your Identity Center instance.

When you remove or add user assignments, we recommend that you review the application’s documentation because you might need to take additional steps to completely onboard or offboard a given user or group. For example, when you remove a user or group assignment, you must also remove the corresponding roles in Amazon Redshift. You can do this by using the DROP ROLE command. For more information, see Managing database security.

Audit user and group access to applications

Let’s consider how you can use the new APIs to help you audit application assignments. In the preceding example, you used the AWS CLI to create and delete assignments to Amazon Redshift. Now, we will show you how to use the new ListApplicationAssignments API to list the groups that are currently assigned to your Amazon Redshift application.

aws sso-admin list-application-assignments --application-arn arn:aws:sso::****************:application/ssoins-****************/apl-****************

The output should look similar to the following — in this case, you have a single group assigned to the application.

{
    "ApplicationAssignments": [
        {
        "ApplicationArn": "arn:aws:sso::****************:application/ssoins-****************/apl-****************",
        "PrincipalId": "********-****-****-****-************",
        "PrincipalType": "GROUP"
        }
    ]
}

To see the group membership, use the PrincipalId information to query Identity Store and get information on the users assigned to the group with a combination of the ListGroupMemberships and DescribeGroupMembership APIs.

If you have several applications that IAM Identity Center manages, you can also create a script to automatically audit those applications. You can run this script periodically in an AWS Lambda function in your environment to maintain oversight of the members that are added to each application.

To get the script for this use case, see the multiple-instance-management-iam-identity-center GitHub repository. The repository includes instructions to deploy the script using Lambda within the AWS Organizations delegated administrator account. After deployment, you can invoke the Lambda function to get .csv files of every IAM Identity Center instance in your organization, the applications assigned to each instance, and the users that have access to those applications.

Conclusion

In this post, you learned how to use the IAM Identity Center application assignment APIs to assign users to Amazon Redshift and remove them from the application when they are no longer part of the organization. You also learned to list which applications are deployed in each account, and which users are assigned to each of those applications.

To learn more about IAM Identity Center, see the AWS IAM Identity Center user guide. To test the application assignment APIs, see the SSO-admin API reference guide.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS IAM Identity Center re:Post or contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Author

Laura Reith

Laura is an Identity Solutions Architect at AWS, where she thrives on helping customers overcome security and identity challenges. In her free time, she enjoys wreck diving and traveling around the world.

Steve Pascoe

Steve Pascoe

Steve is a Senior Technical Product Manager with the AWS Identity team. He delights in empowering customers with creative and unique solutions to everyday problems. Outside of that, he likes to build things with his family through Lego, woodworking, and recently, 3D printing.

sowjir-1.jpeg

Sowjanya Rajavaram

Sowjanya is a Sr Solution Architect who specializes in Identity and Security in AWS. Her entire career has been focused on helping customers of all sizes solve their Identity and Access Management problems. She enjoys traveling and experiencing new cultures and food.

Ayar Labs TeraPHY is Terrifyingly Quick with Fiber Directly Plugging into Chips

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/ayar-labs-teraphy-is-terrifyingly-quick-with-fiber-directly-plugging-into-chips/

At SC23, we saw a terrifyingly quick co-packaged optics demo with the Ayar Labs TeraPHY 4Tbps optical tiles and pluggable connectors

The post Ayar Labs TeraPHY is Terrifyingly Quick with Fiber Directly Plugging into Chips appeared first on ServeTheHome.

Cloudflare named a leader in Forrester Edge Development Platforms Wave, Q4 2023

Post Syndicated from Brendan Irvine-Broque original http://blog.cloudflare.com/forrester-wave-edge-development-2023/

Forrester has recognized Cloudflare as a leader in The Forrester Wave™: Edge Development Platforms, Q4 2023 with the top score in the current offering category.

According to the report by Principal Analyst, Devin Dickerson, “Cloudflare’s edge development platform provides the building blocks enterprises need to create full stack distributed applications and enables developers to take advantage of a globally distributed network of compute, storage and programmable security without being experts on CAP theorem.“

Over one million developers are building applications using the Developer Platform products including Workers, Pages, R2, KV, Queues, Durable Objects, D1, Stream, Images, and more. Developers can easily deploy highly distributed, full-stack applications using Cloudflare’s full suite of compute, storage, and developer services.

Workers make Cloudflare’s network programmable

“ A key strength of the platform is the interoperability with Cloudflare’s programmable global CDN combined with a deployment model that leverages intelligent workload placement.”
– The Forrester Wave™: Edge Development Platforms, Q4 2023

Workers run across Cloudflare’s global network, provide APIs to read from and write directly to the local cache, and expose context from Cloudflare’s CDN directly on the request object that a Worker receives.

This close integration with Cloudflare’s network allows developers to build, protect, and connect globally distributed applications, without deploying to specific regions. Smart Placement optimizes Workers to run in the location that yields the fastest overall performance, whether it’s the location closest to the data, or closest to the user. Hyperdrive automatically pools database connections, allowing Workers running all over the world to reuse them when querying PostgreSQL databases, avoiding the scaling challenges that make it hard to use traditional databases with a serverless architecture. Cron Triggers allow for up to 15 minutes of CPU time, allowing for compute intensive background work.

Cloudflare is beyond edge computing — it’s everywhere computing. We use our network to make your application perform best, shaped by real-world data and tailored to access patterns and programming paradigms.

Deploy distributed systems, without being a distributed systems expert

“ Reference customers consistently call out the ease of onboarding, which sees developers with no prior background delivering workloads across the globe in minutes, and production quality applications within a week. “
– The Forrester Wave™: Edge Development Platforms, Q4 2023

Workers empower any developer to deploy globally distributed applications, without needing to become distributed systems experts or experts in configuring cloud infrastructure.

  • When you deploy a Worker, behind the scenes Cloudflare distributes it across the globe. But to you, it’s a single application that you can run and test locally, using the same open-source JavaScript runtime that your Workers run on in production.
  • When you deploy a Durable Object to coordinate real-time state, you’ve built a distributed application, but instead of having to learn RPC protocols and scale infrastructure, you’ve programmed the whole thing in JavaScript using web standard APIs that front-end developers know and rely on daily.
  • Enqueuing and processing batches of messages with Cloudflare Queues takes adding just a few more lines of JavaScript to an existing Worker.
  • When you create a web application with Cloudflare Pages, you’ve set up a complete continuous build and deployment pipeline with preview URLs, just by connecting to a GitHub repository.

Developers who previously only wrote front-end code are able to build the back end, and make their app real-time and reactive. Teams stuck waiting for infrastructure experts to provision resources are able to start prototyping today rather than next week. Writing and deploying a Worker is familiar and accessible, and this lets engineering teams move faster, with less overhead.

Why are teams able to get started so quickly?

  1. Workers use web standard APIs that front-end developers and anyone building web applications already use every day. Cloudflare was a founding member of the Web-interoperable Runtimes Community Group (WinterCG) and is committed to interoperability across runtimes.
  2. The tools developers already use every day are native to our platform. We publish TypeScript types for all APIs, and support compiling TypeScript when authoring and deploying via the Wrangler CLI or via the code editor in the Cloudflare dashboard — which itself is powered by the popular VSCode editor.
  3. The open-source frameworks that developers prefer to build with are supported. A growing set of APIs from Node.js are available natively in the Workers runtime, allowing existing open source libraries to work on Workers. And increasingly, new open source projects that developers depend on are designed from day one to work across all WinterCG runtimes. Every day, more of the JavaScript ecosystem works on Workers.

Expanding into AI with GPUs, LLMs, and more

“Its superior vision refuses to limit the future footprint to the edge, and their purposeful approach to building out capabilities on the roadmap suggests that it will be increasingly well positioned to take on public cloud hyperscalers for workloads. “
– The Forrester Wave™: Edge Development Platforms, Q4 2023

We are building a complete compute platform for production applications at scale. And as every company and every developer is now building or experimenting with AI, Cloudflare has made GPUs an integrated part of our developer platform. We’ve made it just as easy to get started with AI as we have to deliver a global workload. In mid-November, we hit our goal to have Workers AI Inference running in over 100 cities around the world, and by the end of the 2024 Workers AI will be running in nearly every city Cloudflare has a presence in.

Workers AI allows developers to build applications using the latest open-source AI models, without provisioning any infrastructure or paying for costly unused capacity. We’re extending this to support deploying models directly from Hugging Face to Workers AI, for an even wider set of AI models. And unlike provisioning a VM with a GPU in a specific data center, we’re building this such that we can treat our whole network as one giant compute resource, running models in the right place at the right time to serve developers’ needs.

Beyond model inference, we’re doubling down on supporting web standard APIs and making the WebGPU API available from within the Workers platform. While we’re proud to be recognized as a leading edge platform, we’re not just that —we are a platform for developing full-stack applications, even those that require compute power that just one year ago very few used or needed.

We’re excited to show you what’s next, including a new way to manage secrets across Cloudflare products, improved observability, and better tools for releasing changes. Every day we see more advanced applications built on our platform, and we’re committed to matching that with tools to serve the most mission-critical workloads — the same ones we use ourselves to build our products on our own platform.

Download the report here.

Building our Team in Prague: Meet Martin Votruba

Post Syndicated from Rapid7 original https://blog.rapid7.com/2023/11/27/building-our-team-in-prague-meet-martin-votruba/

Building our Team in Prague: Meet Martin Votruba

From developing driver-assistance software for a luxury car brand to jumping on board an NFT startup, Martin Votruba, Lead Software Engineer, is not one to shy away from a challenge. In September of 2023, joined Rapid7 as the first hire in its new Prague office. Martin is leveraging Rapid7’s excitement and energy of a startup while having the resources and support of an established organization to build a new team in Prague. He sat down to share his experience as one of the first employees in Prague, and discuss how Rapid7’s culture of collaboration and continuous learning helped him build a successful foundation on which to grow his team.

How have your past experiences contributed to how you approach your role today?

At Rapid7, my team’s job is to search for reported vulnerabilities and communicate those within our product (InsightVM) so that our customers can determine whether or not they are at risk. With different software vulnerabilities, each case is unique. This makes our job different from traditional engineering where you follow one recipe or code path and deploy it. I’m constantly drawing inspiration from past challenges and experiences to think about how to approach each new case here. I enjoy the opportunity to be creative in identifying solutions and helping our product deliver the best outcomes to our customers.

What was it that initially attracted you to Rapid7?

To be honest, I had never heard of the company before. It was exciting to see that it was starting a new office in Prague, while also having an established team globally to collaborate and partner with. I was looking for an opportunity to grow and learn from others and was interested in a global company. Being able to maintain the excitement and energy of a startup environment by being part of a new office is a unique opportunity. It also is a really fun environment building its own organic culture as new people are excited about working for Rapid7 and joining us every week.

What is something you didn’t realize or expect about Rapid7’s culture?

As far as culture, it was a nice surprise to see that even though Rapid7 is a global company and has larger structures in place, it isn’t so rigid that you are bogged down by processes or unable to feel you are  making an impact. For example, right after I joined I had an opportunity to be a part of the interview team for some new roles. I was given that trust automatically to help shape what the office looks like and who we are bringing on board.

Another thing that may be surprising to a lot of people is that even though we are a cybersecurity company, you don’t have to be a cybersecurity expert to have a successful career here. I’m still a software engineer – not a cybersecurity expert (although I’ve learned a lot). What I’m responsible for is still core to my expertise as an engineer, I’m just working within a domain and product that happens to be cybersecurity.

How have you been able to build relationships as a new employee?

We have a really interesting program called “Insight Coffee” that encourages people from around the company to set up 1:1s and get to know one another. There’s no agenda, and it’s truly just to learn about another person’s background, experience, or role. The program opens the door for you to reach out and form relationships in a way that is really approachable and encouraged. If I know I’m going to be working closely with someone on a different team, I’ll set up a quick Insight Coffee to get to know them before diving into a project. That way, when we are working together, it helps open up that avenue of communication and understanding, making the entire process or project run more smoothly.

What was your interview experience like?

After talking with the recruiter about the opportunity, my interview consisted of a call with the Hiring Manager, an interview where we talked about the role and Rapid7’s culture, and a technical challenge. The technical challenge was interesting, and is designed to see how you approach solving a specific problem. Even though I was being assessed on my skills, I felt I was supported and encouraged to ask questions if I was stuck or unsure of something. Now that I am on the other side of this process and helping others with their technical challenge, I know it’s important to understand how someone thinks, what questions they ask, and how they approach the challenge. Of course, getting to the right answer or resolution is the goal, but how they get there and how they approach it is equally important when assessing if someone is the right person for the job. As a manager, I want to bring that same level of support to my team, so they know no matter what challenge they are up against, we are all here to work together and find the best solution as a team.

To learn more about Rapid7’s new office in Prague, click here.
View and apply to Rapid7 jobs in Prague here.

[$] A discussion on kernel-maintainer pain points

Post Syndicated from corbet original https://lwn.net/Articles/952146/

A regular feature of the Kernel Maintainers Summit is a session where Linus
Torvalds discusses the problems that he has been encountering. In recent
years, though, there have been relatively few of those problems, so this
year he turned things around a bit by asking
the community
what problems it was seeing instead. He then addressed
them at the Summit in a session covering aspects of the development
community, including feedback to maintainers, diversity (or the
lack thereof), and more.

Security updates for Monday

Post Syndicated from jake original https://lwn.net/Articles/952923/

Security updates have been issued by Debian (freeimage, gimp, gst-plugins-bad1.0, node-json5, opensc, python-requestbuilder, reportbug, strongswan, symfony, thunderbird, and tiff), Fedora (chromium, galera, golang, kubernetes, mariadb, python-asyncssh, thunderbird, vim, and webkitgtk), Gentoo (AIDE, Apptainer, GLib, GNU Libmicrohttpd, Go, GRUB, LibreOffice, MiniDLNA, multipath-tools, Open vSwitch, phpMyAdmin, QtWebEngine, and RenderDoc), Slackware (vim), SUSE (gstreamer-plugins-bad, java-1_8_0-ibm, openvswitch, poppler, slurm, slurm_22_05, slurm_23_02, sqlite3, vim, webkit2gtk3, and xrdp), and Ubuntu (openvswitch and thunderbird).

PipeWire 1.0 released

Post Syndicated from corbet original https://lwn.net/Articles/952848/

PipeWire, the audio/video bus meant to
replace PulseAudio, JACK, and other systems, has reached
1.0
. In celebration, Fedora Magazine is running an
interview with PipeWire creator Wim Taymans
.

PipeWire is an IPC mechanism for multimedia. The most interesting
stuff will happen in the session manager, the modules, the
applications and the tools around all this. I hope to see more cool
tools to route video and set up video filters etc.

Pipewire 1.0 released

Post Syndicated from corbet original https://lwn.net/Articles/952848/

PipeWire, the audio/video bus meant to
replace PulseAudio, JACK, and other systems, has reached
1.0
. In celebration, Fedora Magazine is running an
interview with PipeWire creator Wim Taymans
.

PipeWire is an IPC mechanism for multimedia. The most interesting
stuff will happen in the session manager, the modules, the
applications and the tools around all this. I hope to see more cool
tools to route video and set up video filters etc.

Introducing IAM Access Analyzer custom policy checks

Post Syndicated from Mitch Beaumont original https://aws.amazon.com/blogs/security/introducing-iam-access-analyzer-custom-policy-checks/

AWS Identity and Access Management (IAM) Access Analyzer was launched in late 2019. Access Analyzer guides customers toward least-privilege permissions across Amazon Web Services (AWS) by using analysis techniques, such as automated reasoning, to make it simpler for customers to set, verify, and refine IAM permissions. Today, we are excited to announce the general availability of IAM Access Analyzer custom policy checks, a new IAM Access Analyzer feature that helps customers accurately and proactively check IAM policies for critical permissions and increases in policy permissiveness.

In this post, we’ll show how you can integrate custom policy checks into builder workflows to automate the identification of overly permissive IAM policies and IAM policies that contain permissions that you decide are sensitive or critical.

What is the problem?

Although security teams are responsible for the overall security posture of the organization, developers are the ones creating the applications that require permissions. To enable developers to move fast while maintaining high levels of security, organizations look for ways to safely delegate the ability of developers to author IAM policies. Many AWS customers implement manual IAM policy reviews before deploying developer-authored policies to production environments. Customers follow this practice to try to prevent excessive or unwanted permissions finding their way into production. Depending on the volume and complexity of the policies that need to be reviewed; these reviews can be intensive and take time. The result is a slowdown in development and potential delay in deployment of applications and services. Some customers write custom tooling to remove the manual burden of policy reviews, but this can be costly to build and maintain.

How do custom policy checks solve that problem?

Custom policy checks are a new IAM Access Analyzer capability that helps security teams accurately and proactively identify critical permissions in their policies. Custom policy checks can also tell you if a new version of a policy is more permissive than the previous version. Custom policy checks use automated reasoning, a form of static analysis, to provide a higher level of security assurance in the cloud. For more information, see Formal Reasoning About the Security of Amazon Web Services.

Custom policy checks can be embedded in a continuous integration and continuous delivery (CI/CD) pipeline so that checks can be run against policies without having to deploy the policies. In addition, developers can run custom policy checks from their local development environments and get fast feedback about whether or not the policies they are authoring are in line with your organization’s security standards.

How to analyze IAM policies with custom policy checks

In this section, we provide step-by-step instructions for using custom policy checks to analyze IAM policies.

Prerequisites

To complete the examples in our walkthrough, you will need the following:

  1. An AWS account, and an identity that has permissions to use the AWS services, and create the resources, used in the following examples. For more information, see the full sample code used in this blog post on GitHub.
  2. An installed and configured AWS CLI. For more information, see Configure the AWS CLI.
  3. The AWS Cloud Development Kit (AWS CDK). For installation instructions, refer to Install the AWS CDK.

Example 1: Use custom policy checks to compare two IAM policies and check that one does not grant more access than the other

In this example, you will create two IAM identity policy documents, NewPolicyDocument and ExistingPolicyDocument. You will use the new CheckNoNewAccess API to compare these two policies and check that NewPolicyDocument does not grant more access than ExistingPolicyDocument.

Step 1: Create two IAM identity policy documents

  1. Use the following command to create ExistingPolicyDocument.
    cat << EOF > existing-policy-document.json
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": [
                    "ec2:StartInstances",
                    "ec2:StopInstances"
                ],
                "Resource": "arn:aws:ec2:*:*:instance/*",
                "Condition": {
                    "StringEquals": {
                        "aws:ResourceTag/Owner": "\${aws:username}"
                    }
                }
            }
        ]
    }
    EOF

  2. Use the following command to create NewPolicyDocument.
    cat << EOF > new-policy-document.json
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": [
                    "ec2:StartInstances",
                    "ec2:StopInstances"
                ],
                "Resource": "arn:aws:ec2:*:*:instance/*"
            }
        ]
    }
    EOF

Notice that ExistingPolicyDocument grants access to the ec2:StartInstances and ec2:StopInstances actions if the condition key aws:ResourceTag/Owner resolves to true. In other words, the value of the tag matches the policy variable aws:username. NewPolicyDocument grants access to the same actions, but does not include a condition key.

Step 2: Check the policies by using the AWS CLI

  1. Use the following command to call the CheckNoNewAccess API to check whether NewPolicyDocument grants more access than ExistingPolicyDocument.
    aws accessanalyzer check-no-new-access \
    --new-policy-document file://new-policy-document.json \
    --existing-policy-document file://existing-policy-document.json \
    --policy-type IDENTITY_POLICY

After a moment, you will see a response from Access Analyzer. The response will look similar to the following.

{
    "result": "FAIL",
    "message": "The modified permissions grant new access compared to your existing policy.",
    "reasons": [
        {
            "description": "New access in the statement with index: 1.",
            "statementIndex": 1
        }
    ]
}

In this example, the validation returned a result of FAIL. This is because NewPolicyDocument is missing the condition key, potentially granting any principal with this identity policy attached more access than intended or needed.

Example 2: Use custom policy checks to check that an IAM policy does not contain sensitive permissions

In this example, you will create an IAM identity-based policy that contains a set of permissions. You will use the CheckAccessNotGranted API to check that the new policy does not give permissions to disable AWS CloudTrail or delete any associated trails.

Step 1: Create a new IAM identity policy document

  • Use the following command to create IamPolicyDocument.
    cat << EOF > iam-policy-document.json
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": [
                    "cloudtrail:StopLogging",
                    "cloudtrail:Delete*"
                ],
                "Resource": ["*"] 
            }
        ]
    }
    EOF

Step 2: Check the policy by using the AWS CLI

  • Use the following command to call the CheckAccessNotGranted API to check if the new policy grants permission to the set of sensitive actions. In this example, you are asking Access Analyzer to check that IamPolicyDocument does not contain the actions cloudtrail:StopLogging or cloudtrail:DeleteTrail (passed as a list to the access parameter).
    aws accessanalyzer check-access-not-granted \
    --policy-document file://iam-policy-document.json \
    --access actions=cloudtrail:StopLogging,cloudtrail:DeleteTrail \
    --policy-type IDENTITY_POLICY

Because the policy that you created contains both cloudtrail:StopLogging and cloudtrail:DeleteTrail actions, Access Analyzer returns a FAIL.

{
    "result": "FAIL",
    "message": "The policy document grants access to perform one or more of the listed actions.",
    "reasons": [
        {
            "description": "One or more of the listed actions in the statement with index: 0.",
            "statementIndex": 0
        }
    ]
}

Example 3: Integrate custom policy checks into the developer workflow

Building on the previous two examples, in this example, you will automate the analysis of the IAM policies defined in an AWS CloudFormation template. Figure 1 shows the workflow that will be used. The workflow will initiate each time a pull request is created against the main branch of an AWS CodeCommit repository called my-iam-policy (the commit stage in Figure 1). The first check uses the CheckNoNewAccess API to determine if the updated policy is more permissive than a reference IAM policy. The second check uses the CheckAccessNotGranted API to automatically check for critical permissions within the policy (the validation stage in Figure 1). In both cases, if the updated policy is more permissive, or contains critical permissions, a comment with the results of the validation is posted to the pull request. This information can then be used to decide whether the pull request is merged into the main branch for deployment (the deploy stage is shown in Figure 1).

Figure 1: Diagram of the pipeline that will check policies

Figure 1: Diagram of the pipeline that will check policies

Step 1: Deploy the infrastructure and set up the pipeline

  1. Use the following command to download and unzip the Cloud Development Kit (CDK) project associated with this blog post.
    git clone https://github.com/aws-samples/access-analyzer-automated-policy-analysis-blog.git
    cd ./access-analyzer-automated-policy-analysis-blog

  2. Create a virtual Python environment to contain the project dependencies by using the following command.
    python3 -m venv .venv

  3. Activate the virtual environment with the following command.
    source .venv/bin/activate

  4. Install the project requirements by using the following command.
    pip install -r requirements.txt

  5. Use the following command to update the CDK CLI to the latest major version.
    npm install -g aws-cdk@2 --force

  6. Before you can deploy the CDK project, use the following command to bootstrap your AWS environment. Bootstrapping is the process of creating resources needed for deploying CDK projects. These resources include an Amazon Simple Storage Service (Amazon S3) bucket for storing files and IAM roles that grant permissions needed to perform deployments.
    cdk bootstrap

  7. Finally, use the following command to deploy the pipeline infrastructure.
    cdk deploy --require-approval never

    The deployment will take a few minutes to complete. Feel free to grab a coffee and check back shortly.

    When the deployment completes, there will be two stack outputs listed: one with a name that contains CodeCommitRepo and another with a name that contains ConfigBucket. Make a note of the values of these outputs, because you will need them later.

    The deployed pipeline is displayed in the AWS CodePipeline console and should look similar to the pipeline shown in Figure 2.

    Figure 2: AWS CodePipeline and CodeBuild Management Console view

    Figure 2: AWS CodePipeline and CodeBuild Management Console view

    In addition to initiating when a pull request is created, the newly deployed pipeline can also be initiated when changes to the main branch of the AWS CodeCommit repository are detected. The pipeline has three stages, CheckoutSources, IAMPolicyAnalysis, and deploy. The CheckoutSource stage checks out the contents of the my-iam-policy repository when the pipeline is triggered due to a change in the main branch.

    The IAMPolicyAnalysis stage, which runs after the CheckoutSource stage or when a pull request has been created against the main branch, has two actions. The first action, Check no new access, verifies that changes to the IAM policies in the CloudFormation template do not grant more access than a pre-defined reference policy. The second action, Check access not granted, verifies that those same updates do not grant access to API actions that are deemed sensitive or critical. Finally, the Deploy stage will deploy the resources defined in the CloudFormation template, if the actions in the IAMPolicyAnalysis stage are successful.

    To analyze the IAM policies, the Check no new access and Check access not granted actions depend on a reference policy and a predefined list of API actions, respectively.

  8. Use the following command to create the reference policy.
    cd ../ 
    cat << EOF > cnna-reference-policy.json
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": "*",
                "Resource": "*"
            },
            {
                "Effect": "Deny",
                "Action": "iam:PassRole",
                "Resource": "arn:aws:iam::*:role/my-sensitive-roles/*"
            }
        ]
    }	
    EOF

    This reference policy sets out the maximum permissions for policies that you plan to validate with custom policy checks. The iam:PassRole permission is a permission that allows an IAM principal to pass an IAM role to an AWS service, like Amazon Elastic Compute Cloud (Amazon EC2) or AWS Lambda. The reference policy says that the only way that a policy is more permissive is if it allows iam:PassRole on this group of sensitive resources: arn:aws:iam::*:role/my-sensitive-roles/*”.

    Why might a reference policy be useful? A reference policy helps ensure that a particular combination of actions, resources, and conditions is not allowed in your environment. Reference policies typically allow actions and resources in one statement, then deny the problematic permissions in a second statement. This means that a policy that is more permissive than the reference policy allows access to a permission that the reference policy has denied.

    In this example, a developer who is authorized to create IAM roles could, intentionally or unintentionally, create an IAM role for an AWS service (like EC2 for AWS Lambda) that has permission to pass a privileged role to another service or principal, leading to an escalation of privilege.

  9. Use the following command to create a list of sensitive actions. This list will be parsed during the build pipeline and passed to the CheckAccessNotGranted API. If the policy grants access to one or more of the sensitive actions in this list, a result of FAIL will be returned. To keep this example simple, add a single API action, as follows.
    cat << EOF > sensitive-actions.file
    dynamodb:DeleteTable
    EOF

  10. So that the CodeBuild projects can access the dependencies, use the following command to copy the cnna-reference-policy.file and sensitive-actions.file to an S3 bucket. Refer to the stack outputs you noted earlier and replace <ConfigBucket> with the name of the S3 bucket created in your environment.
    aws s3 cp ./cnna-reference-policy.json s3://<ConfgBucket>/cnna-reference-policy.json
    aws s3 cp ./sensitive-actions.file s3://<ConfigBucket>/sensitive-actions.file

Step 2: Create a new CloudFormation template that defines an IAM policy

With the pipeline deployed, the next step is to clone the repository that was created and populate it with a CloudFormation template that defines an IAM policy.

  1. Install git-remote-codecommit by using the following command.
    pip install git-remote-codecommit

    For more information on installing and configuring git-remote-codecommit, see the AWS CodeCommit User Guide.

  2. With git-remote-codecommit installed, use the following command to clone the my-iam-policy repository from AWS CodeCommit.
    git clone codecommit://my-iam-policy && cd ./my-iam-policy

    If you’ve configured a named profile for use with the AWS CLI, use the following command, replacing <profile> with the name of your named profile.

    git clone codecommit://<profile>@my-iam-policy && cd ./my-iam-policy

  3. Use the following command to create the CloudFormation template in the local clone of the repository.
    cat << EOF > ec2-instance-role.yaml
    ---
    AWSTemplateFormatVersion: 2010-09-09
    Description: CloudFormation Template to deploy base resources for access_analyzer_blog
    Resources:
      EC2Role:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: 2012-10-17
            Statement:
            - Effect: Allow
              Principal:
                Service: ec2.amazonaws.com
              Action: sts:AssumeRole
          Path: /
          Policies:
          - PolicyName: my-application-permissions
            PolicyDocument:
              Version: 2012-10-17
              Statement:
              - Effect: Allow
                Action:
                  - 'ec2:RunInstances'
                  - 'lambda:CreateFunction'
                  - 'lambda:InvokeFunction'
                  - 'dynamodb:Scan'
                  - 'dynamodb:Query'
                  - 'dynamodb:UpdateItem'
                  - 'dynamodb:GetItem'
                Resource: '*'
              - Effect: Allow
                Action:
                  - iam:PassRole 
                Resource: "arn:aws:iam::*:role/my-custom-role"
            
      EC2InstanceProfile:
        Type: AWS::IAM::InstanceProfile
        Properties:
          Path: /
          Roles:
            - !Ref EC2Role
    EOF

The actions in the IAMPolicyValidation stage are run by a CodeBuild project. CodeBuild environments run arbitrary commands that are passed to the project using a buildspec file. Each project has already been configured to use an inline buildspec file.

You can inspect the buildspec file for each project by opening the project’s Build details page as shown in Figure 3.

Figure 3: AWS CodeBuild console and build details

Figure 3: AWS CodeBuild console and build details

Step 3: Run analysis on the IAM policy

The next step involves checking in the first version of the CloudFormation template to the repository and checking two things. First, that the policy does not grant more access than the reference policy. Second, that the policy does not contain any of the sensitive actions defined in the sensitive-actions.file.

  1. To begin tracking the CloudFormation template created earlier, use the following command.
    git add ec2-instance-role.yaml 

  2. Commit the changes you have made to the repository.
    git commit -m 'committing a new CFN template with IAM policy'

  3. Finally, push these changes to the remote repository.
    git push

  4. Pushing these changes will initiate the pipeline. After a few minutes the pipeline should complete successfully. To view the status of the pipeline, do the following:
    1. Navigate to https://<region>.console.aws.amazon.com/codesuite/codepipeline/pipelines (replacing <region> with your AWS Region).
    2. Choose the pipeline called accessanalyzer-pipeline.
    3. Scroll down to the IAMPolicyValidation stage of the pipeline.
    4. For both the check no new access and check access not granted actions, choose View Logs to inspect the log output.
  5. If you inspect the build logs for both the check no new access and check access not granted actions within the pipeline, you should see that there were no blocking or non-blocking findings, similar to what is shown in Figure 4. This indicates that the policy was validated successfully. In other words, the policy was not more permissive than the reference policy, and it did not include any of the critical permissions.
    Figure 4: CodeBuild log entry confirming that the IAM policy was successfully validated

    Figure 4: CodeBuild log entry confirming that the IAM policy was successfully validated

Step 4: Create a pull request to merge a new update to the CloudFormation template

In this step, you will make a change to the IAM policy in the CloudFormation template. The change deliberately makes the policy grant more access than the reference policy. The change also includes a critical permission.

  1. Use the following command to create a new branch called add-new-permissions in the local clone of the repository.
    git checkout -b add-new-permissions

  2. Next, edit the IAM policy in ec2-instance-role.yaml to include an additional API action, dynamodb:Delete* and update the resource property of the inline policy to use an IAM role in the /my-sensitive-roles/*” path. You can copy the following example, if you’re unsure of how to do this.
    ---
    AWSTemplateFormatVersion: 2010-09-09
    Description: CloudFormation Template to deploy base resources for access_analyzer_blog
    Resources:
      EC2Role:
        Type: AWS::IAM::Role
        Properties:
          AssumeRolePolicyDocument:
            Version: 2012-10-17
            Statement:
            - Effect: Allow
              Principal:
                Service: ec2.amazonaws.com
              Action: sts:AssumeRole
          Path: /
          Policies:
          - PolicyName: my-application-permissions
            PolicyDocument:
              Version: 2012-10-17
              Statement:
              - Effect: Allow
                Action:
                  - 'ec2:RunInstances'
                  - 'lambda:CreateFunction'
                  - 'lambda:InvokeFunction'
                  - 'dynamodb:Scan'
                  - 'dynamodb:Query'
                  - 'dynamodb:UpdateItem'
                  - 'dynamodb:GetItem'
                  - 'dynamodb:Delete*'
                Resource: '*'
              - Effect: Allow
                Action:
                  - iam:PassRole 
                Resource: "arn:aws:iam::*:role/my-sensitive-roles/my-custom-admin-role"
            
      EC2InstanceProfile:
        Type: AWS::IAM::InstanceProfile
        Properties:
          Path: /
          Roles:
            - !Ref EC2Role

  3. Commit the policy change and push the updated policy document to the repo by using the following commands.
    git add ec2-instance-role.yaml 
    git commit -m "adding new permission and allowing my ec2 instance to assume a pass sensitive IAM role"

  4. The add-new-permissions branch is currently a local branch. Use the following command to push the branch to the remote repository. This action will not initiate the pipeline, because the pipeline only runs when changes are made to the repository’s main branch.
    git push -u origin add-new-permissions

  5. With the new branch and changes pushed to the repository, follow these steps to create a pull request:
    1. Navigate to https://console.aws.amazon.com/codesuite/codecommit/repositories (don’t forget to the switch to the correct Region).
    2. Choose the repository called my-iam-policy.
    3. Choose the branch add-new-permissions from the drop-down list at the top of the repository screen.
      Figure 5: my-iam-policy repository with new branch available

      Figure 5: my-iam-policy repository with new branch available

    4. Choose Create pull request.
    5. Enter a title and description for the pull request.
    6. (Optional) Scroll down to see the differences between the current version and new version of the CloudFormation template highlighted.
    7. Choose Create pull request.
  6. The creation of the pull request will Initiate the pipeline to fetch the CloudFormation template from the repository and run the check no new access and check access not granted analysis actions.
  7. After a few minutes, choose the Activity tab for the pull request. You should see a comment from the pipeline that contains the results of the failed validation.
    Figure 6: Results from the failed validation posted as a comment to the pull request

    Figure 6: Results from the failed validation posted as a comment to the pull request

Why did the validations fail?

The updated IAM role and inline policy failed validation for two reasons. First, the reference policy said that no one should have more permissions than the reference policy does. The reference policy in this example included a deny statement for the iam:PassRole permission with a resource of /my-sensitive-role/*. The new created inline policy included an allow statement for the iam:PassRole permission with a resource of arn:aws:iam::*:role/my-sensitive-roles/my-custom-admin-role. In other words, the new policy had more permissions than the reference policy.

Second, the list of critical permissions included the dynamodb:DeleteTable permission. The inline policy included a statement that would allow the EC2 instance to perform the dynamodb:DeleteTable action.

Cleanup

Use the following command to delete the infrastructure that was provisioned as part of the examples in this blog post.

cdk destroy 

Conclusion

In this post, I introduced you to two new IAM Access Analyzer APIs: CheckNoNewAccess and CheckAccessNotGranted. The main example in the post demonstrated one way in which you can use these APIs to automate security testing throughout the development lifecycle. The example did this by integrating both APIs into the developer workflow and validating the developer-authored IAM policy when the developer created a pull request to merge changes into the repository’s main branch. The automation helped the developer to get feedback about the problems with the IAM policy quickly, allowing the developer to take action in a timely way. This is often referred to as shifting security left — identifying misconfigurations early and automatically supporting an iterative, fail-fast model of continuous development and testing. Ultimately, this enables teams to make security an inherent part of a system’s design and architecture and can speed up product development workflow.

You can find the full sample code used in this blog post on GitHub.

To learn more about IAM Access Analyzer and the new custom policy checks feature, see the IAM Access Analyzer documentation.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Mitch Beaumont

Mitch Beaumont

Mitch is a Principal Solutions Architect for AWS, based in Sydney, Australia. Mitch works with some of Australia’s largest financial services customers, helping them to continually raise the security bar for the products and features that they build and ship. Outside of work, Mitch enjoys spending time with his family, photography, and surfing.

Author

Matt Luttrell

Matt is a Principal Solutions Architect on the AWS Identity Solutions team. When he’s not spending time chasing his kids around, he enjoys skiing, cycling, and the occasional video game.

The collective thoughts of the interwebz