This
Google blog entry looks at some zero-day Android exploits that were
detected and makes it clear what the stakes are.
We assess with high confidence that these exploits were packaged by
a single commercial surveillance company, Cytrox, and sold to
different government-backed actors who used them in at least the
three campaigns discussed below. Consistent with findings from
CitizenLab, we assess likely government-backed actors purchasing
these exploits are operating (at least) in Egypt, Armenia, Greece,
Madagascar, Côte d’Ivoire, Serbia, Spain and Indonesia.
Our team had some fun experimenting with Python 3.9-nogil, the results of which will be reported in an upcoming blog post. In the meantime, we saw an opportunity to dive deeper into the history of the global interpreter lock (GIL), including why it makes Python so easy to integrate with and the tradeoff between ease and performance.
We reached out to Barry Warsaw, a preeminent Python developer and contributor, because we could think of no one better to break down the evolution of the GIL for us. Barry is a longtime Python core developer, former release manager and steering council member, and PSF Fellow. He was project lead for the GNU Mailman mailing list manager. Barry, along with contributor Paweł Polewicz, a backend software developer and longtime Python user, went above and beyond anything we could have imagined, developing this comprehensive deep dive into the GIL and its evolution over the years. Thanks also go to Larry Hastings for his review and feedback.
If Python’s GIL is something you are curious about, we’d love to hear your thoughts in the comments. We’ll let Barry take it from here.
—The Editors
First Things First: What Is the GIL?
The Python GIL, or Global Interpreter Lock, is a mechanism in CPython (the most common implementation of Python) that serves to serialize operations involving the Python bytecode interpreter, and provides useful safety guarantees for internal object and interpreter state. While providing many benefits, as the discussion below will show, the GIL also prevents CPython from achieving full multicore performance.
In simplest terms, the GIL is a lock (or mutex) that allows only a single operating system thread to run the central Python bytecode interpreter loop. Normally, when multiple threads can access shared state, such as global interpreter or object internal state, a programmer would need to implement fine grained locks to prevent one thread from stomping on the state set by another thread. The GIL removes the need for these fine grained locks because it imposes a global lock that prevents multiple threads from mutating this state at the same time.
In this post, I’ll explore the pros and cons of the GIL, and the many efforts over the years to remove it, including some recent exciting developments.
Humble Beginnings
Back in November 1994, I was invited to a little gathering of programming language enthusiasts to meet the Dutch inventor of a relatively new and little known object-oriented language. This three day workshop was organized by my friends and former colleagues at the National Institute of Standards and Technology (NIST) in Gaithersburg, MD. I came with extensive experience in languages from C, C++, FORTH, LISP, Perl, TCL, and Objective-C and enjoyed learning and playing with new programming languages.
Of course, the Dutch inventor was Guido van Rossum and his little language was Python. I think most of us in attendance knew there was something special about Python and Guido, but it probably would have shocked us to know that Python would even be around almost 30 years later, let alone have the scope, impact, or popularity it enjoys today. For me personally, it was a life-changing moment.
A few years ago, I gave a talk at BayPiggies that took a retrospective look at the evolution of Python from version 1.1 in October 1994 (just before the abovementioned workshop), through the Python 2 series, and up to Python 3.7, the newest release of the language at the time. In many ways, Python 1.1 would be recognizable by today’s modern Python programmer. In other ways, you’d wonder how Python was ever usable without features that were introduced in the intervening years.
Can you imagine not having the tuple() or list() built-ins, or docstrings, or class exceptions, keyword arguments, *args, **kws, packages, or even different operators for assignment and equality tests? It was fun to go back through all those old changelogs and remember what it was like as each of the features we now take for granted were introduced, often in those early days with absolutely no regard for backward compatibility.
I managed to find the agenda for that first Python workshop, and one of the items to be discussed was “Improving the efficiency of Python (e.g., by using a different garbage collection scheme).” I don’t remember any of the details of that discussion, but even then, and from its start, Python employed a reference counting memory management scheme (the cyclic garbage detector being many years away yet). Reference counting is a simple way of managing your objects in a higher level language where you don’t directly allocate or free your memory. One of Guido’s early guiding principles for Python, and which has served Python well over the years, is to keep it as simple as possible while still being effective, useful, and fun.
The Basics of Reference Counting
Reference counting is simple; as it says on the tin, the interpreter keeps a counter that tracks every reference to an object. For example, binding an object to a variable (such as by an assignment) increases that object’s reference count by one. Appending an object to a list also increases its reference count by one. Removing an object from the list decreases that object’s reference count by one. When a variable goes out of scope, the reference count of the object the variable is bound to is decreased by one again. We call this reference count the object’s “refcount” and these two operations “incref” and “decref” respectively.
When an object’s refcount goes to zero it means there are no more live references to the object, so it can be safely freed (and finalized) because nothing in the program can reach that object anymore1. As these objects are deallocated, any references to objects they hold are also decref’d, and so on. Refcounting gives the Python interpreter a very simple mechanism for freeing garbage and more importantly, it allows for humans to reason about Python’s memory management, both from the point of view of the Python programmer, and from the vantage point of the C extension writer, who doesn’t have the luxury of all that reference counting happening automatically.
This is a crucial point: When we talk about “Python” we generally mean “CPython,” the implementation of the runtime written in C2. The C programmer working on the CPython runtime, and the module author writing extensions for Python in C (for performance or to integrate with some system library) does have to worry about all the nitty gritty details of when to incref or decref an object. Get this wrong and your extension can leak memory or double free an object, either way wreaking havoc on your system. Fortunately, Python has clear rules to follow and good documentation, but it can still be difficult to get refcounting right in complex situations, such as when proper error handling leads to multiple exit paths from a function.
Here’s Where the GIL Comes In: Reference Counting and Concurrency
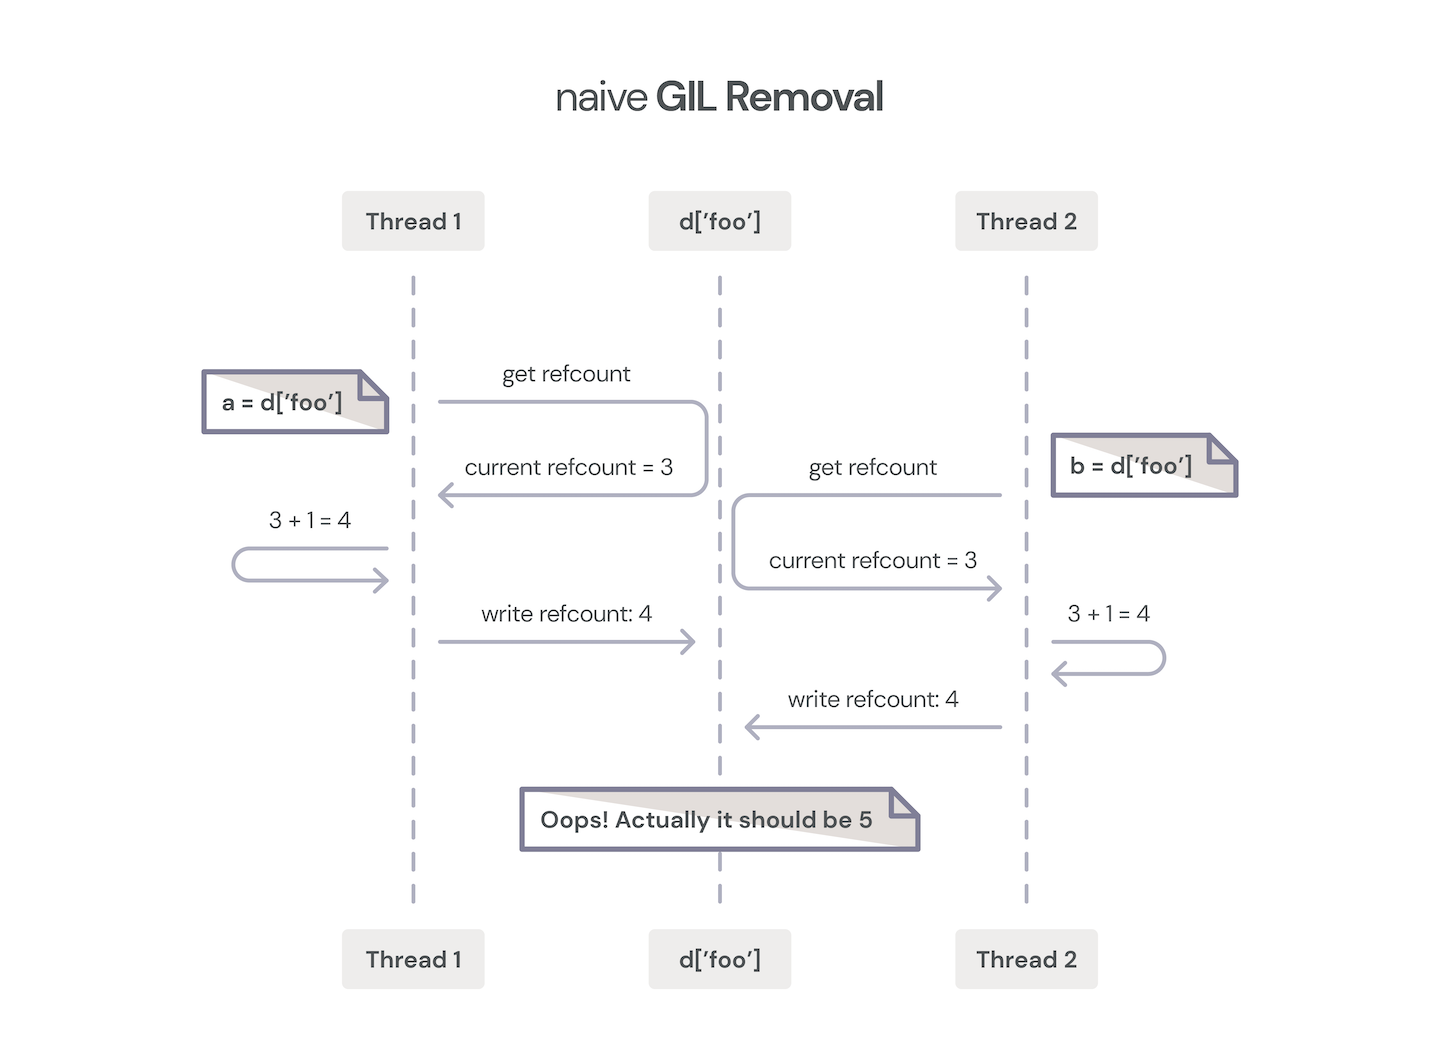
One of the key simplifying rules is that the programmer doesn’t have to worry about concurrency when managing Python reference counting. Think about the situation where you have multiple threads, each inserting and removing a Python object from a collection such as a list or dictionary. Because those threads may run at any time and in any order, you would normally have to be extremely defensive in how you incref and decref those objects, and it would be way too easy to get this wrong. You could crash Python, or worse, if you didn’t implement the proper locks around your incref and decref operations. Having to worry about all that would make your C code very complicated and likely pretty error prone. The CPython implementation also has global and static variables which are vulnerable to race conditions3.
In keeping with Python’s principles, in 1992, when Guido first began to implement threading support in Python, he utilized a simple mechanism to keep this manageable for a wide range of Python programmers and extension authors: a Global Interpreter Lock—the infamous GIL!
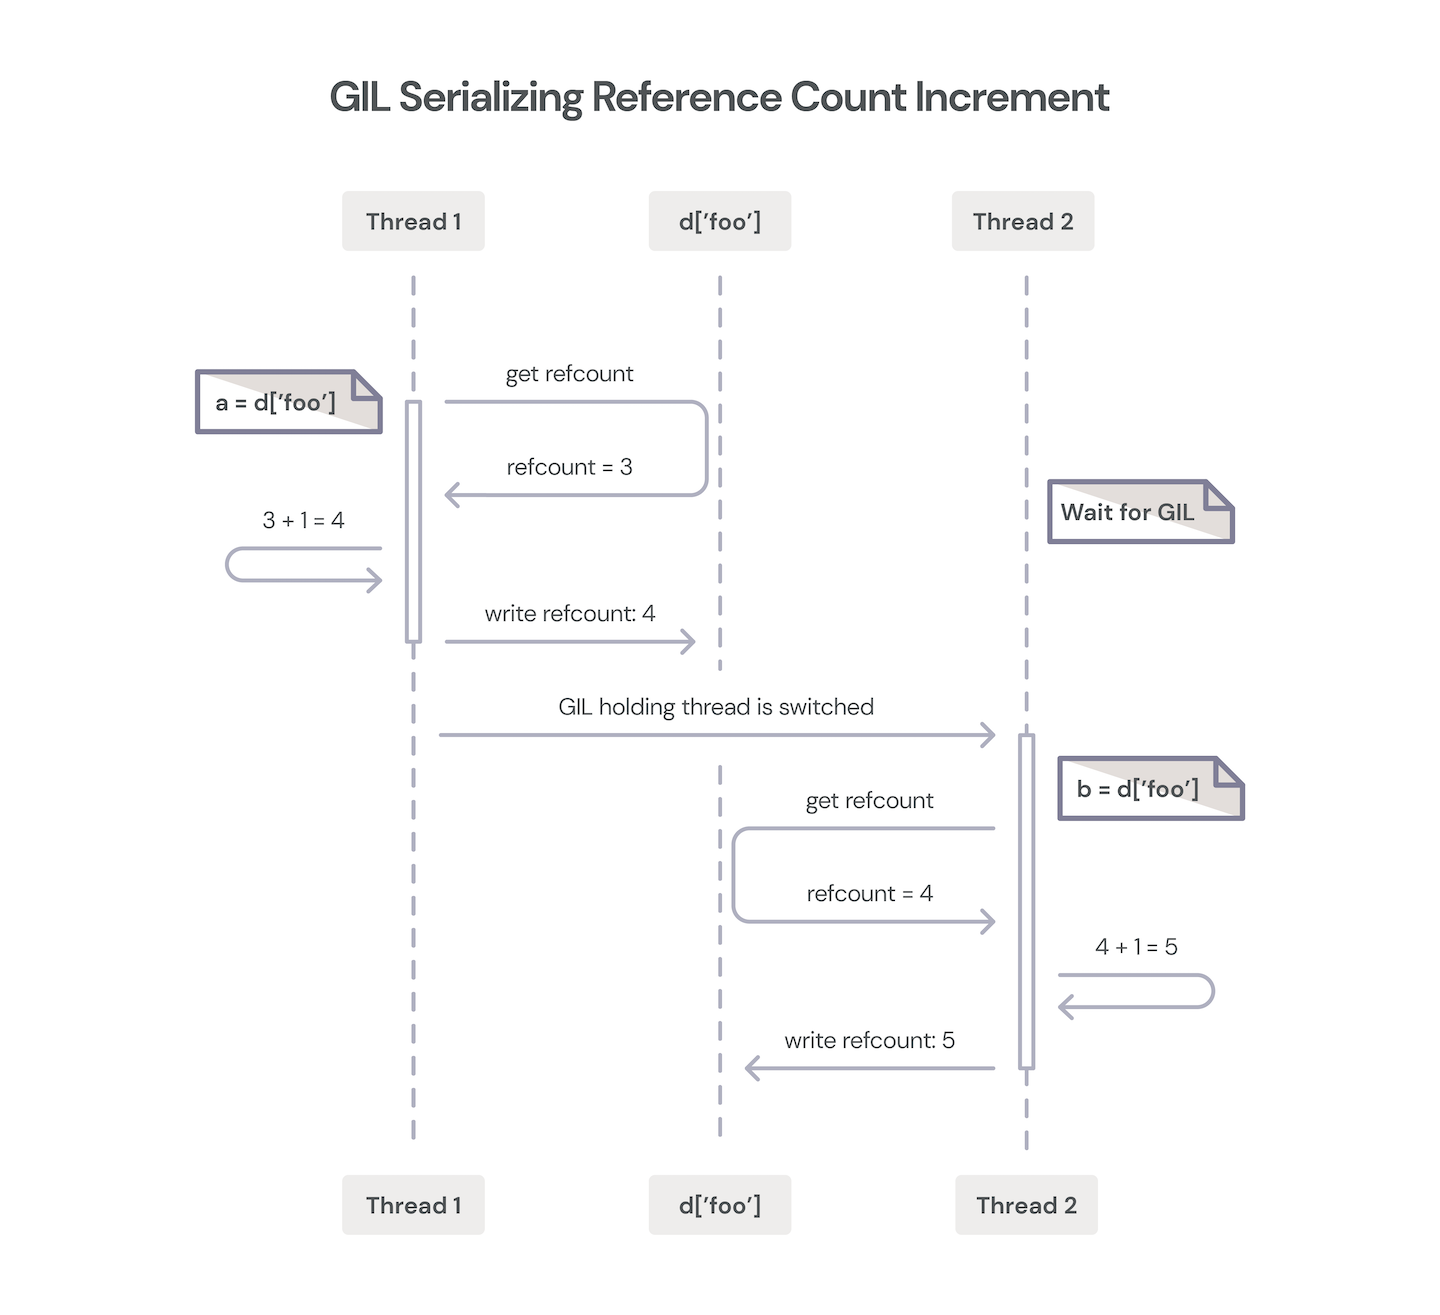
Because the Python interpreter itself is not thread-safe, the GIL allows only one thread to execute Python bytecode at a time, and thus serializes all access to Python objects. So, barring bugs, it is impossible for multiple threads to stomp on each other’s reference count operations. There are C API functions to release and acquire the GIL around blocking I/O or compute intensive functions that don’t touch Python objects, and these provide boundaries for the interpreter to switch to other Python-executing threads.
Two threads incrementing an object reference counter.
Thus, we gain significant C implementation simplicity at the expense of some parallelism. Modern Python has many ways to work around this limitation, from asyncio to subprocesses and multiprocessing, which all work fine if they align with your requirements. Python also surfaces operating system threading primitives, but these can’t take full advantage of multicore operations because of the GIL.
Advantages of the GIL
Back in the early days of Python, we didn’t have the prevalence of multicore processors, so this all worked fine. These days, modern programming languages are more multicore friendly, and the GIL gets a bad rap. Before we explore the work to remove the GIL, it’s important to understand just how much benefit and mileage Python has gotten out of it.
One important aspect of the GIL is that it simplifies the programming model for extension module authors. When writing extension modules in C, C++, or any other low-level language with access to the internals of the Python interpreter, extension authors would normally have to ensure that there are no race conditions that could corrupt the internal state of Python objects. Concurrency is hard to get right, especially so in low-level languages, and one mistake can corrupt the entire state of the interpreter4. For an extension author, it can already be challenging to ensure all your increfs and decrefs are properly balanced, especially for any branches, early exits, or error conditions, and this would be monumentally more difficult if the author also had to contend with concurrent execution. The GIL provides an important simplifying model of object access (including refcount manipulation) because it ensures that only one thread of execution can mutate Python objects at a time5.
There are important performance benefits of the GIL for single-threaded operations as well. Without the GIL, Python would need some other way of ensuring that object refcounts are safe from corruption due to, for example, race conditions between threads, such as when adding or removing objects from any mutable collection (lists, dictionaries, sets) that are shared across threads. These techniques can be very expensive as some of the experiments described later showed. Ensuring that Python interpreter is safe for multithreaded use cases degrades its performance for the single-threaded use case. The GIL’s low performance overhead really shines for single-threaded operations, including I/O-multiplexed programs where libraries like asyncio are used, and this is still a predominant use of Python. Finer-grained locks also increase the chances of deadlocks, which isn’t possible with the GIL.
Also, one of the reasons Python is so popular today is that it had so many extensions written for it over the years. One of the reasons there are so many powerful extension modules, whether we like to admit it or not, is that the GIL makes those extensions easier to write.
And yet, Python programmers have long dreamed of being able to run multithreaded Python programs to take full advantage of all the cores available on modern computing platforms. Even today’s watches and phones have multiple cores, whereas in Python’s early days, multicore systems were rare. Here we are 30 or so years later, and while the GIL has served Python well, in order to take advantage of what clearly seems to be more than a passing fad, Python’s GIL often gets in the way of true high-performance multithreaded concurrency.
Attempting to Remove the GIL
Two threads incrementing object reference counter without GIL protection.
Over the years, many attempts have been made to remove the GIL.
1999: Greg Stein’s “Free Threading”
Circa 1999, Greg Stein’s “free threading” work was one of the first (successful!) attempts to remove the GIL. It made the locks much more fine-grained and moved global variables inside the interpreter into a structure, which we actually still use today. It had the unfortunate side effect however, of making your Python code multiple times slower. Thus, while the free threading work was a great experiment, it was far too impractical to adopt.
2015: Larry Hasting’s Gilectomy
Years later (circa 2015), Larry Hasting’s wonderfully named Gilectomy project tried a different approach to remove the GIL. In Larry’s PyCon 2016 talk, he discusses four technical considerations that must be addressed when removing the GIL:
Reference Counting: Race conditions on updating the refcount between multiple threads as described previously.
Globals and Statics: These include interpreter global housekeeping variables, and shared singleton objects. Much work has been done over the years to move these globals into per-thread structures. Eric Snow’s work on multiple interpreters (aka “subinterpreters”) has also made a lot of progress on isolating these variables into structures that represent an interpreter “instance” where theoretically each instance could run on a separate core. There are even proposals for making some of those shared singleton objects immortal, such that reference counting race conditions would have no effect on the lifetime of those objects. An interesting related proposal would move the GIL into a per-interpreter data structure, which could lead to the ability to run an isolated interpreter instance per core (with limitations).
C Extensions: Keep in mind that there is a huge ecosystem of C extension modules, and much of Python’s power comes from these extension modules, of which NumPy is a hugely popular example. These extensions have never had to worry about parallelism or re-entrancy because they’ve always relied on the GIL to serialize their operations. At a minimum, a GIL-less Python will require recompilation of extension modules, and some or all may require some level of source code modifications as well. These changes may include protecting internal (non-Python) data structures for concurrency, using functional APIs for refcount modification instead of accessing refcount fields directly, not assuming that Python collections are stable over iteration, etc.
Atomicity: Operations such as adding or deleting objects from Python collections such as lists and dictionaries actually involve a number of steps internally. To the Python developer, these all appear to be atomic operations, and in fact they are, thanks to the GIL.
Larry also identifies what he calls three “political” considerations, but which I think are more in the realm of the social contract between Python developers and Python users:
Removing the GIL should not hurt performance for single-threaded or I/O-bound multithreaded code.
We can’t break existing C extensions as described above6.
Don’t let GIL removal make the CPython interpreter too complicated or difficult to understand. One of Guido’s guiding principles, and a subtle reason for Python’s huge success, is that even with complicated features such as exception handling, asyncio, generators, etc. Python’s C core is still relatively easy to learn and understand. This makes it easy for new contributors to engage with Python core development, an absolutely essential quality if you want your language to thrive and grow for its next 30 years as much as it has for its previous 30.
Larry’s Gilectomy work is quite impressive, and I highly recommend watching any of his PyCon talks for deep technical dives, served with a healthy dose of humor. As Larry points out, removing the GIL isn’t actually the hard part. The hard part is doing so while adhering to the above mentioned technical and social constraints, retaining Python’s single-threaded performance, and building a mechanism that scales with the number of cores. This latter constraint is important because if we’re going to enable multicore operations, we want to ensure that Python’s performance doesn’t hit a plateau at four or eight cores.
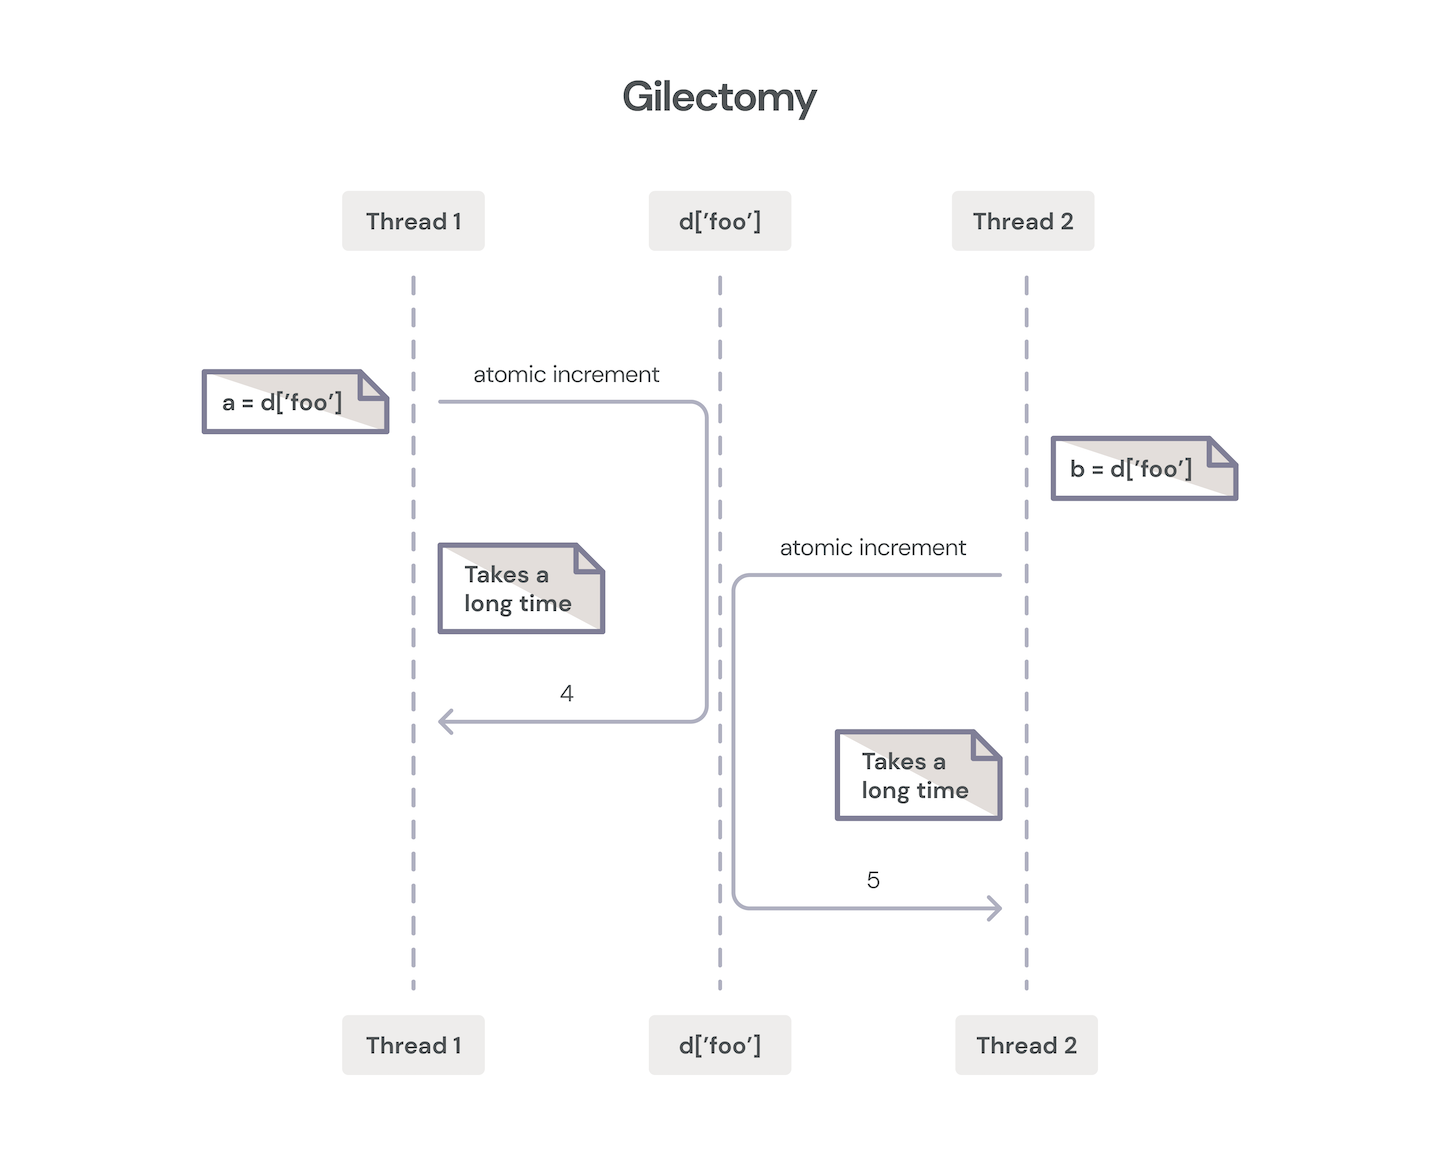
So, why did the Gilectomy branch fail (measured in units of “didn’t get adopted by CPython”)? For the most part, the performance and complexity constraints couldn’t be met. One of the biggest hits on performance wasn’t actually lock contention on objects. The early Gilectomy work relied on atomic increment and decrement CPU instructions, which destroyed cache consistency, and caused a high overhead of communication on the intercore bus to ensure atomicity.
Intercore atomic incr/decr communication.
Later, Larry experimented with a technique borrowed from garbage collection research called “buffered reference counting,” essentially a transaction log for refcount changes. However, contention on transaction logs required further modifications to segregate logs by threads and by increment and decrement operations. This led to non-realtime garbage collection events on refcounts reaching zero, which broke features such as Python’s weakref objects.
Interestingly, another hotspot turned out to be what’s called “obmalloc,” which is a small block allocator that improves performance over just using system malloc for everything. We’ll touch on this again later. Solving all these knock-on effects (such as repairing the cyclic garbage collector) led to increased complexity of the implementation, making the chance that it would ever get merged into Python highly unlikely.
Before we leave this topic to look at some new and exciting work, let’s return briefly to Eric Snow’s work on multiple interpreters (aka subinterpreters). PEP 554 proposes to add a new standard library module called “interpreters” which would expose the underlying work that Eric has been doing to isolate interpreter state out of global variables internal to CPython. One such global state is, of course, the GIL. With or without Python-level access to these features, if the GIL could be moved from global state to per-interpreter state, each interpreter instance could theoretically run concurrently with the others. You could therefore attach a different interpreter instance to each thread, and these could run Python code in parallel. This is definitely a work in progress and it’s unclear whether multiple interpreters will deliver on its promises of this kind of limited concurrency. I say “limited” because without full GIL removal, there is significant complexity in sharing Python objects between interpreters, which would almost certainly be necessary. Issues such as ownership (which thread owns which object) and safe mutability would need to be resolved. PEP 554 proposes some solutions to these problems and more, so we’ll have to keep an eye on this work. But even multiple interpreters don’t provide the same true concurrency that full GIL removal promises.
The Future of the GIL: Where Do We Go From Here?
And now we come full-circle, because Python’s popularity, vast influence, and reach is also one of the reasons why it still seems impossible to remove the GIL while retaining single-threaded performance and not breaking the entire ecosystem of extension modules.
Yet here we are with PyCon 2022 just concluded, and there is renewed excitement for Sam Gross’ “nogil” work, which holds the promise of a performant, GIL-less CPython with minimal backward incompatibilities at both the Python and C layers. While some performance regressions are inevitable, Sam’s work also utilizes a number of clever techniques to claw these regressions back through other internal performance improvements.
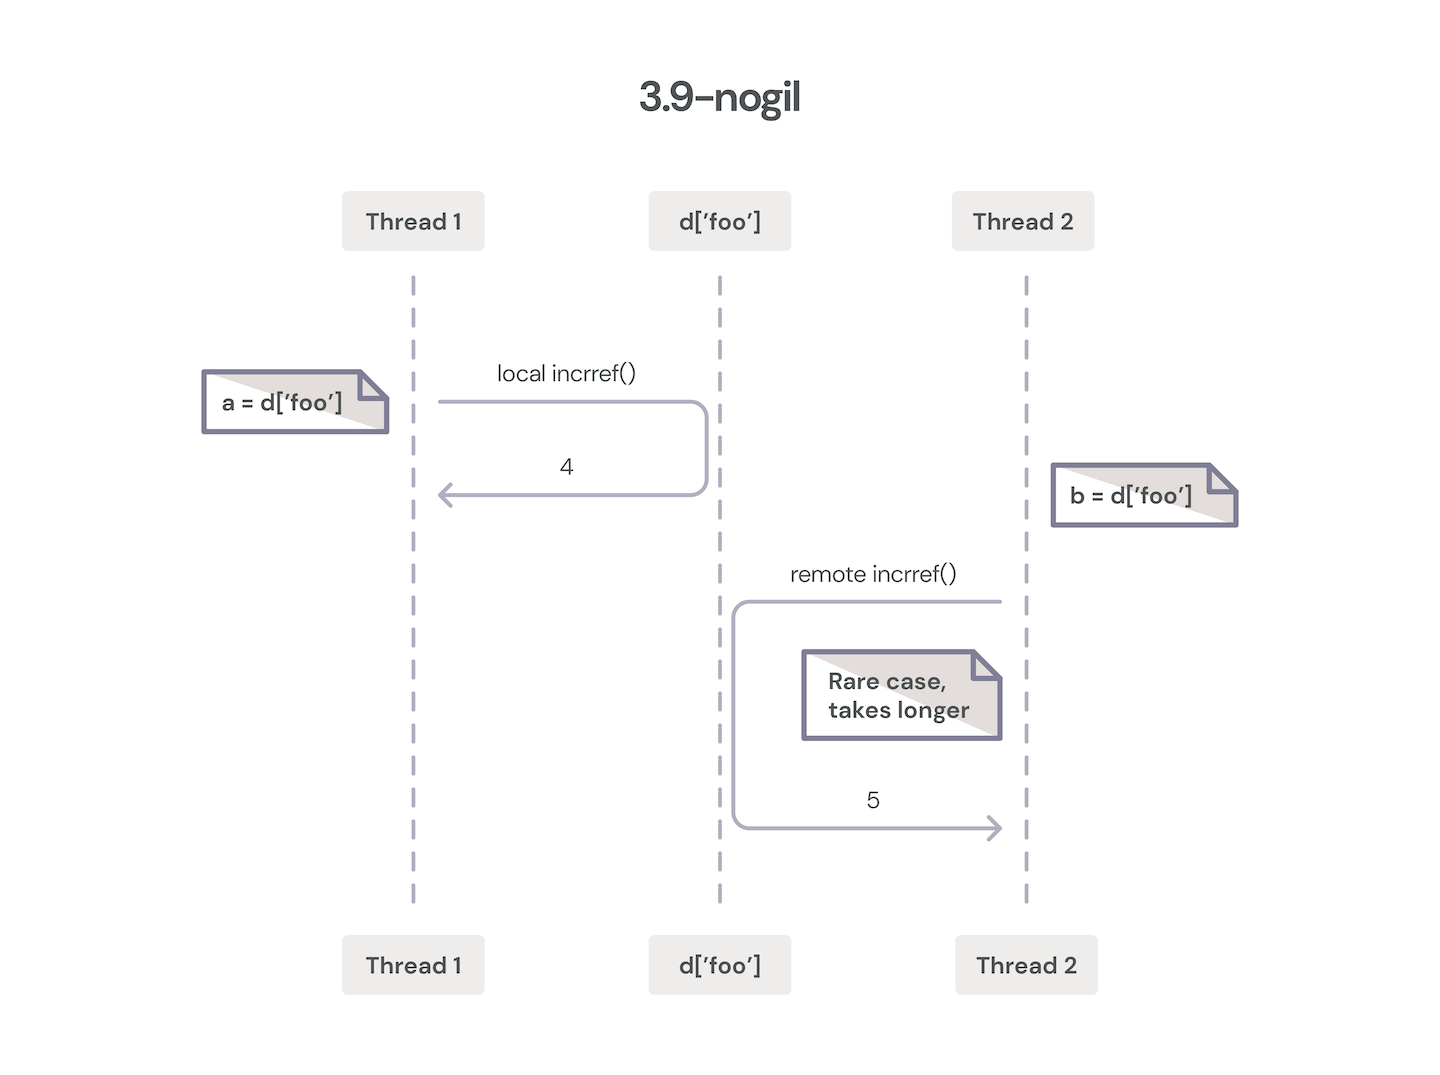
Two threads incrementing object reference counter on Sam Gross’ “nogil” branch.
With these improvements as well as the work that Guido’s team at Microsoft is doing with its Faster CPython project, there is renewed hope and excitement that the GIL can be removed while retaining or even improving overall performance, and not giving up on backward compatibility. It will clearly be a multi-year effort.
Sam’s nogil project aims to support a concurrency sweet spot. It promises that data race conditions will never corrupt Python’s virtual machine, but it leaves the integrity of user-level data structures to the programmer. Concurrency is hard, and many Python programs and libraries benefit from the implicit GIL constraints, but solving this is a harder problem outside the scope of the nogil project. Data science applications are one big potential domain to benefit from true multiprocessor enabled concurrency in Python.
There are a number of techniques that the nogil project utilizes to remove the GIL bottleneck. As mentioned, the project also employs a number of other virtual machine improvements to regain some of the performance inevitably lost by removing the GIL. I won’t go into too much detail about these improvements, but it’s helpful to note that where these are independent of nogil, they can and are being investigated along with other work Guido’s team is doing to improve the overall performance of CPython.
Python 3.11 recently entered beta (and thus feature freeze), and with it we’ll see significant performance improvements, which no doubt will continue in future Python releases. When and if nogil is adopted, some of those performance gains may regress to support nogil. Whether and how this will be a good trade-off will be an interesting point of analysis and debate in the coming years. In Sam’s original paper, he proposes a runtime switch to choose between nogil and normal GIL operation, however this was discussed at the PyCon 2022 Language Summit, and the consensus was that this wouldn’t be practical. Thus, as the nogil experiment moves forward, it will be enabled by a compile-time switch.
At a high level, the removal of the GIL is afforded by changes in three areas: the memory allocator, reference counting, and concurrent collection protections. Each of these are deep topics on their own, so we’ll only be able to touch on them briefly.
nogil Part 1: Memory Allocators
Because everything in Python is an object, and most objects are dynamically allocated on the heap, the CPython interpreter implements several levels of memory allocators, and provides C API functions for allocating and freeing memory. This allows it to efficiently allocate blocks of raw memory from the operating system, and to subdivide and manage those blocks based on the type of objects being placed into them. For example, integers have different memory requirements than dictionaries, so having object-specific memory managers for these (and other) types of objects makes memory management inside the interpreter much more efficient.
CPython also employs a small object allocator, called pymalloc, which improves performance for allocating and freeing objects smaller than or equal to 512 bytes. This only touches on the complexities of memory management inside the interpreter. The point of all this complexity is to enable more efficient object creation and destruction, but it also allows for features like memory allocation debugging and custom memory allocators.
The nogil works takes advantage of this pluggability to utilize a general purpose, highly efficient, thread-safe memory allocator developed by Daan Leijen at Microsoft called mimalloc. mimalloc itself is worthy of an in-depth look, but for our purposes it’s enough to know that the mimalloc design is extremely well tuned to efficient and thread-safe allocation of memory blocks. The nogil project utilizes these structures for the implementation of dictionaries and other collection types which minimize the need for locks on non-mutating access, as well as managing garbage collected objects7 with minimal bookkeeping. mimalloc has also been highly tuned for performance and thread-safety.
nogil Part 2: Reference Counting
nogil also makes several changes to reference counting, although it does so in a clever way that minimizes changes to the Limited C API, but does not preserve the stable ABI. This means that while extension modules must be recompiled, their source code may not require modification, outside of a few known corner cases8.
One very promising idea is to make some objects effectively immortal, which I touched on earlier. True, False, None and some other objects in practice never actually see their refcounts go to zero, and so they stay alive for the entire lifetime of the Python process. By utilizing the least significant bits of the object’s reference count field for bookkeeping, nogil can make the refcounting macros no-op for these objects, thus avoiding all contention across threads for these fields.
nogil uses a form of biased reference counting to split an object’s refcount into two buckets. For refcount changes in the thread that owns the object, these “local” changes can be made by the more efficient conventional (non-atomic) forms. For changing the refcount of objects in a different thread, an atomic operation is necessary for safe concurrent modification of a “shared” refcount. The thread that owns the object can then combine this local and shared refcount for garbage collection purposes, and it can give up ownership when its local refcount goes to zero. This is performant when most object accesses are local to the owning thread, which is generally the case. nogil’s biased reference counting scheme can utilize mimalloc’s memory pools to efficiently keep track of the owning threads.
However, some objects are typically owned by multiple threads and are not immortal, and for these types of objects (e.g., functions, modules), a deferred reference counting scheme is employed. Incref and decref act as normal for these objects, but when the interpreter loads these objects onto its internal stack, the refcounts are not modified. The utility of this technique is limited to objects that are only deallocated during garbage collection because they are typically involved in reference cycles.
The garbage collector is also modified to ensure that it only runs at safe boundary points, such as a bytecode execution boundary. The current nogil implementation of garbage collection is single-threaded and stops the world, so it is thread-safe. It repurposes some of the existing C API functions to ensure that it doesn’t wait on threads that are blocked on I/O.
nogil Part 3: Concurrent Collection Protections
The third high-level technique that nogil uses to enable concurrency is to implement an efficient algorithm for locking container objects, such as dictionaries and lists, when mutating them. To maintain thread-safety, there’s just no way around employing locks for this. However, nogil optimizes for objects that are primarily modified in a single thread, and it admits that objects which are frequently and concurrently modified may need a different design.
Sam’s nogil paper goes into considerable detail about the locking algorithm, but at a high level it relies on container versioning (where every modification to a container bumps a “version” counter so the various read accesses can know whether the container has been modified between distinct reads or not), biased reference counting, and various mimalloc features to optimize for fast track, single-threaded, no modification reads while amortizing the cost of locking for writes against the other expensive operations a typical container write operation imposes.
The Last Word and Some Predictions
Sam Gross’ nogil project is impressive. He’s managed to satisfy most of the difficult constraints that have thwarted previous attempts at removing the GIL, including minimizing as much as possible the impact on single-threaded performance (and trading general interpreter performance improvements for the cost of removing the GIL), maintaining (mostly) Python’s C API backward compatibility to not force changes on the entire extension module ecosystem, and all the while (Despite the length of this article!) preserving the readability and comprehensibility of the CPython interpreter.
You’ve no doubt noticed that the rabbit hole goes pretty deep, and we’ve only explored some of the tunnels in this particular burrow. Fortunately, Python’s semantics and CPython’s implementation has been well documented over its 30 year life, so there are plenty of opportunities for self-exploration…and contributions! It will take sustained engagement through careful and incremental steps to bring these ideas to fruition. The future certainly is exciting.
If I had to guess, I would say that we’ll see features like multiple interpreters provide some concurrency value in the next release or so, with GIL removal five years (and thus five releases) or more away. However many of the techniques described here are already being experimented with and may show up earlier. Python 3.11 will have many noticeable performance improvements, with plenty of room for additional performance work in future releases. These will give the nogil work room to continue its experimentation at true multicore performance.
For a language and interpreter that has gone from a small group of lucky and prescient enthusiasts to a worldwide top-tier programming language, I think there is more excitement and optimism for Python’s future than ever. And that’s not even talking about game changers such as PyScript.
Stay tuned for a post that introduces the performance experiments the Backblaze team has done with Python 3.9-nogil and Backblaze B2 Cloud Storage. Have you experimented with Python 3.9-nogil? Let us know in the comments.
Barry Warsaw
Barry has been a Python core developer since 1994 and is listed as the first non-Dutch contributor to Python. He worked with Python’s inventor, Guido van Rossum, at CNRI when Guido, and Python development, moved from the Netherlands to the USA. He has been a Python release manager and steering council member, created and named the Python Enhancement (PEP) process, and is involved in Python development to this day. He was the project leader for GNU Mailman, and for a while maintained Jython, the implementation of Python built on the JVM. He is currently a senior staff engineer at LinkedIn, a semiprofessional bass player, and tai chi enthusiast. All opinions and commentary expressed in this article are his own.
Pawel has been a backend developer since 2002. He built the largest e-radio station on the planet in 2006-2007, worked as a QA manager for six years, and finally, started Reef Technologies, a software house highly specialized in building Python backends for startups.
Reference cycles are not only possible but surprisingly common, and these can keep graphs of unreachable objects alive indefinitely. Python 2.0 added a generational cyclic garbage collector to handle these cases. The details are tricky and worthy of an article in its own right.
CPython is also called the “reference implementation” because new features show up there first, even though they are defined for the generic “Python language.” It’s also the most popular implementation, and typically what people think of when they say “Python.”
Much work has been done over the years to reduce these as much as possible.
It’s even worse than this implies. Debugging concurrency problems is notoriously difficult because the conditions that lead to the bug are nearly impossible to reproduce, and few tools exist to help.
Instrumenting concurrent code to try to capture the behavior can introduce subtle timing differences that hide the problem. The industry has even coined the term, “Heisenbug,” to describe the complexity of this class of bug.
Some extension modules also use the GIL as a conveniently available mutex to protect concurrent access to their own, non-Python resources.
It doesn’t seem possible to completely satisfy this constraint in any attempt to remove the GIL.
I.e., the aforementioned cyclic reference garbage collector.
Such as when the extension module peeks and pokes inside CPython data structures directly or via various macros, instead of using the C API’s functional interfaces.
In a fast-paced talk at PyCon 2022 in Salt Lake City,
Utah, Pablo Galindo Salgado described some changes he and others have made
to the error reporting for CPython 3.10. He painted a picture of a
rather baffling set of syntax errors reported by earlier interpreter
versions and how they have improved. This work is not done by any means,
he said, and encouraged attendees to get involved in making error reporting
even better in future Python versions.
If you follow cybersecurity, you’ve likely seen one of the many articles written recently on the one-year anniversary of the Colonial Pipeline ransomware attack, which saw fuel delivery suspended for six days, disrupting air and road travel across the southeastern states of the US. The Colonial attack was the biggest cyberattack against US critical infrastructure, making it something of a game-changer in the realm of ransomware, so it is absolutely worth noting the passage of time and investigating what’s changed since.
This blog will do that, but I’ll take a slightly different tack, as I’m also marking the anniversary of the Ransomware Task Force’s (RTF) report, which offered 48 recommendations for policymakers wanting to deter, disrupt, prepare, and respond to ransomware attacks. The report was issued a week prior to the Colonial attack.
Last week, I participated in an excellent event to mark the one-year anniversary of the RTF report. During the session, various ransomware experts discussed how the ransomware landscape has evolved over the past year, how government action has shaped this, and what more needs to be done. The Institute for Security and Technology (IST), which convenes and runs the RTF, has issued a paper capturing the points above. This blog offers my own thoughts on the matter, but it’s not at all exhaustive, and I recommend giving the official paper a read.
High-profile attacks raised the stakes
Looking back over the past year, in many ways, the Colonial attack – along with ransomware attacks on the Irish Health Service Executive (HSE) and JBS, the largest meat processing company in the world, all of which occurred during May 2021 – highlighted the exact concerns outlined in the RTF report. Specifically, the RTF had been convened based on the view that the high level of attacks against healthcare and other critical services through the pandemic made ransomware a matter of national security for those countries that are highly targeted.
In light of this, one of the most fundamental recommendations of the report was that this be acknowledged and met with a senior leadership and cross-governmental response. The Colonial attack resulted in President Biden addressing the issue of ransomware on national television. Subsequently, we have seen a huge cross-governmental focus on ransomware, with measures announced from departments including Homeland Security, Treasury, Justice, and State. We’ve also seen both Congress and the White House working on the issue. And while the US government has been the most vocal in its response, we have seen other governments also focusing on this issue as a priority and working together to amplify the impact of their action.
In June 2021, the Group of Seven (G7) governments of the world’s wealthiest democracies addressed ransomware at its annual summit. The resulting Communique capturing the group’s commitments includes pledges to work together to address the threat. In October 2021, the White House hosted the governments of 30 nations to discuss ransomware. The event launched the Counter Ransomware Initiative (CRI), committing to collaborate together to find solutions to reduce the ransomware threat. The CRI has identified key themes for further exploration and action, with a similar focus on deterring and disrupting attacks and driving adoption of greater cyber resilience.
Status of the RTF recommendations
This is all heartening to see and strongly aligns with the ethos and recommendations of the RTF recommendations. Drilling down into more of the details, there are many further areas of alignment, including the launch of coordinated awareness programs, introduction of sanctions, scrutiny of cryptocurrency regulations, and a focus on incident reporting regulations. The RTF paper provides a great deal more detail on these areas of alignment and the progress that has been made, as well as the areas that need more focus.
This, I believe, is the key point: A great deal of progress has been made, both in terms of building understanding of the problem and in developing alignment and collaboration among stakeholders, yet there is a great deal more work to be done. The partnerships between multiple governments — and between the public and private sectors — are hugely important for improving our odds against the attackers, but progress will not happen overnight. It will take time to see the real impact of the measures already taken, and there are yet measures to be determined, developed, and implemented.
Uncertain times
We must keep our eye on the ball and stay engaged, which is not easy when there are so many other demands on governments’ and business leaders’ limited time and resources. The Russia/Ukraine conflict has undoubtedly been a very time-consuming area of focus, though expectations that offensive cyber operations would be a key element of the Russian action have perhaps helped increase awareness of the need for cyber resilience. The economic downturn is another huge pressure and will almost certainly reduce critical infrastructure providers’ investments in cybersecurity as the cost of business increases in other areas, resulting in budget cuts. While both of these developments may distract governments and business leaders from ransomware, they may also increase ransomware activity as economic deprivation and job scarcity encourage more people to turn to cybercrime to make a living.
According to law enforcement and other government agencies, as well as the cyber insurance sector, the reports of ransomware incidents are slowing down or declining. Due to a long-standing lack of consistent incident reporting, it’s hard to contextualize this, and while we very much hope it points to a reduction in attacks, we can’t say that that’s the case. Security researchers report that activity on the dark web seems to be continuing at pace with 2021, a record year for ransomware attacks. It’s possible that the shift in view from law enforcement could be due to fears that involving them will result in regulatory repercussions; reports to insurers could be down due to the introduction of more stringent requirements for claims.
The point is that it’s too early to tell, which is why we need to maintain a focus on the issue and seek out data points and anecdotal evidence to help us understand the impact of the government action taken so far, so we can continue to explore and adjust our approach. An ongoing focus, continued collaboration, and more data will help ensure we put as much pressure as possible on ransomware actors and the governments and systems that allow them to flourish. Over time, this is how we will make progress to reduce the ransomware threat.
Security updates have been issued by Debian (firefox-esr and openldap), Fedora (curl), Oracle (kernel and kernel-container), Red Hat (maven:3.5), SUSE (cacti, cacti-spine, firefox, go1.18, openldap2, python-requests, rsyslog, and slurm_20_11), and Ubuntu (firefox, htmldoc, libpng, libxfixes, libxrender, thunderbird, and vim).
The policy for the first time directs that good-faith security research should not be charged. Good faith security research means accessing a computer solely for purposes of good-faith testing, investigation, and/or correction of a security flaw or vulnerability, where such activity is carried out in a manner designed to avoid any harm to individuals or the public, and where the information derived from the activity is used primarily to promote the security or safety of the class of devices, machines, or online services to which the accessed computer belongs, or those who use such devices, machines, or online services.
[…]
The new policy states explicitly the longstanding practice that “the department’s goals for CFAA enforcement are to promote privacy and cybersecurity by upholding the legal right of individuals, network owners, operators, and other persons to ensure the confidentiality, integrity, and availability of information stored in their information systems.” Accordingly, the policy clarifies that hypothetical CFAA violations that have concerned some courts and commentators are not to be charged. Embellishing an online dating profile contrary to the terms of service of the dating website; creating fictional accounts on hiring, housing, or rental websites; using a pseudonym on a social networking site that prohibits them; checking sports scores at work; paying bills at work; or violating an access restriction contained in a term of service are not themselves sufficient to warrant federal criminal charges. The policy focuses the department’s resources on cases where a defendant is either not authorized at all to access a computer or was authorized to access one part of a computer—such as one email account—and, despite knowing about that restriction, accessed a part of the computer to which his authorized access did not extend, such as other users’ emails.
All young people deserve meaningful opportunities to learn how to create with digital technologies. But according to UNESCO, as much as 40% of people around the world don’t have access to education in a language they speak or understand. At the Raspberry Pi Foundation, we offer more than 200 free online projects that people all over the world use to learn about computing, coding, and creating things with digital technologies. To make these projects more accessible, we’ve published over 1700 translated versions so far, in 32 different languages. You can check out these translated resources by visiting projects.raspberrypi.org and choosing your language from the drop-down menu.
Two young children in Uganda code on a laptop at a CoderDojo session.
Most of this translation work was completed by an amazing community of volunteer translators. In 2021 alone, learners engaged in more than 570,000 learning experiences in languages other than English using our projects.
So how do we know it’s important to put in the effort to make our projects available in many different languages? Various studies show that learning in one’s first language leads to better educational and social outcomes.
Improved access and attainment for girls
Education policy specialists Chloe O’Gara and Nancy Kendall describe in a USAID-funded guide document (1996, p. 100) that girls living in multilingual communities are less likely to know the official language of school instruction than boys, because girls’ lives tend to be more restricted to home and family, where they have fewer opportunities to become proficient in a second language. These restrictions limit their access to education, and if they go to school, they are more likely to have a limited understanding of the dominant language, and therefore learn less. Observations in research studies (Hovens, 2002; Benson 2002a, 2002b) suggest that making education available in a local language greatly increases female students’ opportunities for educational access and attainment.
In rural India, a group of girls cluster around a computer.
Improved self-efficacy
Research studies conducted in Guinea and Senegal (Clemons & Yerende, 2009) suggest that education in a local language, which is more likely to focus on the learner’s circumstances, community, and learning and development needs, increases the learner’s belief in their abilities and skills, compared to education in a dominant language.
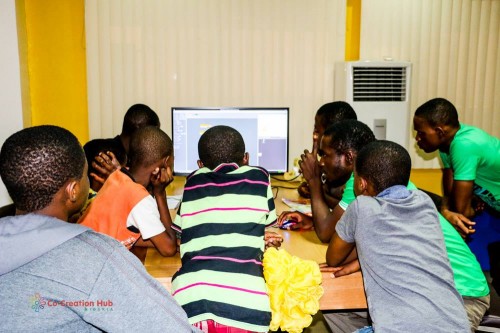
Young people program in Scratch on a Raspberry Pi, at Co-creation Hub, Nigeria.
Improved test scores
Learning in a language other than one’s own has a negative effect on learning outcomes, especially for learners living in poverty. For example, a UNESCO-funded case study in Honduras showed that 94% of pupils learned reading skills if their home language was the same as the language of assessment. In contrast, among pupils who spoke a different language at home, this proportion dropped to 62%. Similarly, a UNESCO-funded case study in Guatemala showed that when students were able to learn in a bilingual environment, attendance and promotion rates increased, while rates of repetition and dropout rates decreased. Moreover, students attained higher scores in all subjects and skills, including the mastery of the dominant language (UNESCO Global Education Monitoring Report, Policy Paper 24, February 2016).
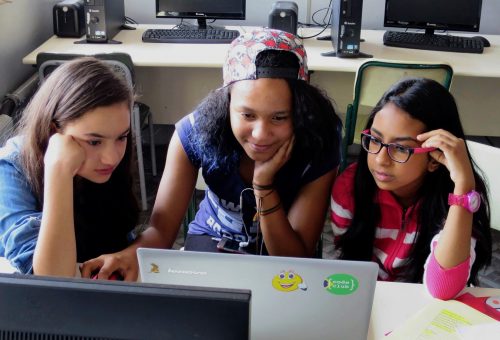
Three girls in Brazil code on a laptop in a Code Club session.
Improved acquisition of programming concepts
A survey conducted by a researcher from the University of California San Diego showed that non-native English speakers found it challenging to learn programming languages when the majority of instructional materials and technical communications were only available in English (Guo, 2018). Moreover, a computing education research study of the association between local language use and the rate at which young people learn to program showed that beginners who learned to program in a programming language with keywords and environment localised into their primary language demonstrated new programming concepts at a faster rate, compared with beginners from the same language group who learned using a programming interface in English (Dasgupta & Hill, 2017).
You can help with translations and empower young people
It is clear from these studies that in order to achieve the most impact and to benefit disadvantaged and underserved communities, educational initiatives must work to make learning resources available in the language that learners are most familiar with.
By translating our learning resources, we not only support people who have English as a second language, we also make the resources useful for people who don’t speak any English — estimated as four out of every five people on Earth.
If you’re interested in helping us translate our learning resources, which are completely free, you can find out more at rpf.io/translate.
I am excited to announce that I have joined Cloudflare as Managing Director for the Middle East and Turkey (MET) region. Having worked in the domain of cyber security for more than two decades, I can see that Cloudflare is genuine in its mission of building a better Internet that is fast, safe and reliable for everyone. Being part of this journey that touches everyone’s life is surely an exciting thing to do, and I look forward to putting my experience in play towards successfully achieving this goal.
Cloudflare has been associated with delivering fast content over cloud in a most reliable and secure manner, accounting for at least 20% of the global Internet traffic. Cloudflare can cater for and support all types of organizations (businesses and public sector) including those with a social mission. The Middle East and Turkey as an emerging market is characterized by a relatively young population, with 70% of it being under the age of 30. This dynamic youth segment has an insatiable demand for both content and knowledge. To that extent, there has been a rapid uptake in Internet use, and digital transformation initiatives have significantly accelerated over the past couple of years; this trend represents an opportunity for Cloudflare to add considerable value to regional enterprises and in doing so, increase its footprint and market share.
Personally, building a regional presence and delivering business growth for global software and technology providers is something that I’ve always enjoyed doing throughout my career and I look forward to helping Cloudflare successfully establish the right level of presence in this fast-growing and dynamic market.
I join Cloudflare with over two decades of experience, mostly in the cybersecurity and software industry, where over the past years I helped global technology providers establish and expand presence and operation in the emerging markets, particularly in the Middle East and Turkey. Prior to joining Cloudflare, I was the Managing Director and Head of Sales for Emerging Markets at CyberRes, the cybersecurity line of business at MicroFocus, managing the sales and business development across the Middle East, Africa, Brazil, Russia, CIS and CEE. Before that I led StarLink Value Added Distribution as their CEO across a 22 country operation, managing their annual business of close to $500M. In addition, I held several leadership positions at major technology vendors such as Symantec, BlueCoat, Fortinet and CyberGuard.
So after all this experience, why did I join Cloudflare?
I enjoy launching operations from inception in the region. Building successful teams that can deliver future incremental growth and objectives and supporting our customers is an exciting challenge. Moreover, the MET region made up of 13 countries with fast-growing and innovation-driven economies presents a unique growth opportunity for Cloudflare to tap into.
I can confidently say that the Middle East and Turkey markets are nowadays at the forefront of technology and early adopters of disruptive technologies such as cloud on a global scale.
This is being driven by many factors such as Digital Transformation where several countries have embraced ambitious programs transforming them into true digital economies. Cloud uptake has accelerated over the past few years in the region and the necessary regulatory frameworks and related compliance policies are now in place to propel enterprises into the next phase of leveraging the benefits of cloud. This transformation is further accelerated as earlier mentioned, by a mostly young and content demanding population-that content being gaming, entertainment, educational, sports or online retail.
The recent pandemic has for sure played a major role in building up this momentum and increasing the urgency in speeding up such a transition.
The parallel increase of cyber threats and associated breaches, puts Cloudflare in an unparalleled and unique position to deliver the required content in a reliable, fast and secure manner to individuals, businesses and public sector alike, elevating the levels of productivity and performance in addition to reducing complexity for users.
To do that, Cloudflare has built a global network and infrastructure across 275 cities around the world with 27 in the MET region, delivering the same connectivity at 50ms performance for more than 95% of customers. The innovation path is stunning. Not only do we provide best in class cyber security solutions with Cloudflare’s SASE security platform, Cloudflare One, a Zero Trust network-as-a-service platform that dynamically connects users to enterprise resources, with identity-based security controls delivered close to users, wherever they are, but we also offer an open strong developer platform with Cloudflare Workers. As we just had our Platform Week, I invite you to check our latest announcements.
Looking ahead
Having spoken to so many customers in the region, I understand that nowadays more than ever, they need to be able to grow their operations by focusing on their core mission without having to worry about their technology. Cloudflare appears to me as one of the most innovative customer-centric companies in the market. More than just technology, we are on a mission to help to build a fast, reliable and secure Internet for a maximum number of people, businesses, and public organizations.
I look forward to contributing towards the future of digital transformation in the Middle East and Turkey, while delivering solutions that will support all the innovative projects that are already on their way or in the pipeline.
Cloudflare has an exceptional company culture with key values such as diversity, principle, collaboration, innovation and transparency. One of my goals is to build a successful team through empowering current team members and attracting future talents that would all contribute towards this journey. Therefore, I encourage anyone sharing the same ambitions and interested in joining our winning team to keep track of our new roles by exploring open positions
I am extremely proud to launch our regional base out of Dubai, to be followed by additional regional expansions in the future. Currently, Cloudflare has 27 data centers distributed across major cities in the MET region, and we have plans to add more in the near future such as the Jeddah datacenter recently announced. All this to cope with the growth in demand that we are forecasting and to help us position Cloudflare as the brand of choice in the region.
Version
3.16.0 of the Alpine Linux distribution has been released. Significant
changes include a switch to tmpfs for the /tmp directory, the
splitting out of a number of NetworkManager plugins into separate packages,
the removal of Python 2, and a lot of updated packages; see the
release notes for more information.
Let’s decompose the name C7g: the “C” instance family is designed for compute-intensive workloads. This is the 7th generation of this instance family. And the “g” means it is based on AWS Graviton, the silicon designed by AWS. These instances are the first instances to be powered by the latest generation of AWS Graviton, the Graviton3 processors.
As you bring more diverse workloads to the cloud, and as your compute, storage, and networking demands increase at a rapid pace, you are asking us to push the price performance boundary even further so that you can accelerate your migration to the cloud and optimize your costs. Additionally, you are looking for more energy-efficient compute options to help you reduce your carbon footprint and achieve your sustainability goals. We do this by working back from your requests, and innovating at a rapid pace across all levels of the AWS infrastructure. Our Graviton chips offer better performance at lower cost along with enhanced capabilities. For example, AWS Graviton3 processors offer you enhanced security with always-on memory encryption, dedicated caches for every vCPU, and support for pointer authentication.
Let’s illustrate this with numbers. When we launched Graviton2-based instances, they provided up to 40 percent better price/performance for a wide variety of workloads over comparable fifth-generation x86-based instances. We now have 12 instance families (M6g, M6gd, C6g, C6gd, C6gn, R6g, R6gd, T4g, X2gd, Im4gn, Is4gen, and G5g) that are powered by AWS Graviton2 processors that provide significant price performance benefits for a wide range of workloads. In 2021, we saw tens of thousands of AWS customers take advantage of this innovation by using Graviton2-based EC2 instances.
Our next generation, Graviton3 processors, deliver up to 25 percent higher performance, up to 2x higher floating-point performance, and 50 percent faster memory access based on leading-edge DDR5 memory technology compared with Graviton2 processors.
Graviton3 also uses up to 60 percent less energy for the same performance as comparable EC2 instances, which helps you reduce your carbon footprint.
Snap Inc, known for its popular social media services such as Snapchat and Bitmoji, adopted AWS Graviton2-based instances to optimize their price performance on Amazon EC2. Aaron Sheldon, software engineer at Snap, told us: “We trialed the new AWS Graviton3-based Amazon EC2 C7g instances and found that they provide significant performance improvements on real workloads compared to previous generation C6g instances. We are excited to migrate our Graviton2-based workloads to Graviton3, including messaging, storage, and friend graph workloads.”
The C7g instances are available in eight sizes with 1, 2, 4, 8, 16, 32, 48, and 64 vCPUs. C7g instances support configurations up to 128 GiB of memory, 30 Gbps of network performance, and 20 Gbps of Amazon Elastic Block Store (EBS) performance. These instances are powered by the AWS Nitro System, a combination of dedicated hardware and a lightweight hypervisor.
The following table summarizes the key characteristics of each instance type in this family.
Instance Name
vCPUs
Memory
Network Bandwidth
EBS Bandwidth
c7g.medium
1
2 GiB
up to 12.5 Gbps
up to 10 Gbps
c7g.large
2
4 GiB
up to 12.5 Gbps
up to 10 Gbps
c7g.xlarge
4
8 GiB
up to 12.5 Gbps
up to 10 Gbps
c7g.2xlarge
8
16 GiB
up to 15 Gbps
up to 10 Gbps
c7g.4xlarge
16
32 GiB
up to 15 Gbps
up to 10 Gbps
c7g.8xlarge
32
64 GiB
15 Gbps
10 Gbps
c7g.12xlarge
48
96 GiB
22.5 Gbps
15 Gbps
c7g.16xlarge
64
128 GiB
30 Gbps
20 Gbps
C7g instances are initially available in US East (N. Virginia) and US West (Oregon) AWS Regions; other Regions will be added shortly after launch.
As usual, you can purchase C7g capacity on demand, as Reserved Instances, or as Spot instances, and use your Saving Plans. The pricing details are available on the EC2 pricing page.
I have the chance to talk with AWS customers on a daily basis, and many of my discussions are around price performance and the sustainability of their workloads. With more than 500 instance types to choose from, one question I often receive is: what are the workloads that would benefit from C7g?
You will find that C7g instances provide the best price performance within their instance families for a broad spectrum of compute-intensive workloads, including application servers, micro services, high-performance computing, electronic design automation, gaming, media encoding, or CPU-based ML inference. These instances are ideal for all Linux-based workloads, including containerized and micro service-based applications built using Amazon Elastic Kubernetes Service (EKS), Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Container Registry, Kubernetes, and Docker, and written in popular programming languages such as C/C++, Rust, Go, Java, Python, .NET Core, Node.js, Ruby, and PHP.
The next question I receive is: given that Graviton instances are based on Arm architecture, how difficult is it to migrate from x86?
Graviton3 instances are supported by a broad choice of operating systems, independent software vendors, container services, agents, and developer tools, enabling you to migrate your workloads with minimal effort.
Applications and scripts written in high-level programming languages such as Python, Node.js, Ruby, Java, or PHP will typically just require a redeployment. Applications written in lower-level programming languages such as C/C++, Rust, or Go will require a re-compilation.
For those of you building with serverless, we have also released Graviton support for AWS Fargate and AWS Lambda, extending the price, efficiency, and performance benefits of Graviton to serverless workloads. Lambda functions using Graviton2 can see up to 34 percent better price/performance.
We do our part in this shared responsibility model, and now, it is your turn. You can use our innovations and tools to help you optimize your workloads and only use the resources you need. Take the occasion to write clever code that uses fewer CPU cycles, less storage, or less network bandwidth. And be sure to select energy-efficient options, such as Graviton3-based instance types or managed services, when deploying your code.
If you’d like to get started with Graviton-based instances for free, we also just reintroduced the free trial on T4g.small instances for up to 750 hours/month until the end of this year (December 31, 2022).
This is the right place to quickly learn about recent AWS news from last week, in just about five minutes or less. This week, I have collected a couple of news items that might be of interest to you, the IT professionals, developers, system administrators, or any type of builders that have their hands on the AWS console, the CLI, or that are writing code.
Last Week’s Launches The launches that caught my attention last week are the following:
EC2 now supports NitroTPM and SecureBoot – A Trusted Platform Module is often a discrete chip in a computer where you can store secrets and release them to the operating system only when the system is in a known good state. You typically use TPM modules to store operating-system-level volume encryption keys, such as the ones used by BitLocker on Windows or LUKS. NitroTPM is a virtual TPM module available on selected instance families that allows you to deploy your workloads depending on TPM functionalities on EC2 instances.
Amazon EC2 Auto Scaling now backfills predictive scaling forecasts so you can quickly validate forecast accuracy. Auto Scaling Predictive Scaling is a capability of Auto Scaling that allows you to scale your fleet in and out based on observed usage patterns. It uses AI/ML to predict when your fleet needs more or less capacity. It allows you to scale a fleet in advance of the scaling event and have the fleet prepared at peak times. The new backfills shows you how predictive scaling would have scaled your fleet during the last 14 days. This allows you to quickly decide if the predictive scaling policy is accurate for your applications by comparing the demand and capacity forecasts against actual demand immediately after you create a predictive scaling policy.
AWS Backup adds support for two new managed file systems,Amazon FSx for OpenZFS and Amazon Fsx for NetApp ONTAP. These additions helps you meet your centralized data protection and regulatory compliance needs. You can now use AWS Backup’s policy-based capabilities to centrally protect Amazon FSx for NetApp ONTAP or Amazon Fsx for OpenZFS, along with the other AWS services for storage, database, and compute that AWS Backup supports.
AWS App Mesh now supports IPv6 – AWS App Mesh is a service mesh that provides application-level networking to make it easy for your services to communicate with each other across multiple types of compute infrastructure. The new support for IPv6 allows you to support workloads running in IPv6 networks and to invoke App Mesh APIs over IPv6. This helps you meet IPv6 compliance requirements, and removes the need for complex networking configuration to handle address translation between IPv4 and IPv6.
Amazon Chime SDK now supports video background replacement and blur on iOS and Android. When you want to integrate audio and video call capabilities in your mobile applications, the Chime SDK is the easiest way to get started. It provides an easy-to-use API that uses the scalable and robust Amazon Chime backend to power your communications. For example, Slack is using Chime as backend for the communications in their apps. The Chime SDK client libraries for iOS and Android now include video background replacement and blur, which developers can use to reduce visual distractions and help increase visual privacy for mobile users on iOS and Android.
Other AWS News Some other updates and news that you may have missed:
Amazon Redshift: Ten years of continuous reinvention. This is an Amazon Redshift research paper that will be presented at a leading international forum for database researchers. The authors reflect on how far the first petabyte-scale cloud data warehouse has advanced since it was announced ten years ago.
Improve Your Security at the Edge with AWS IoT Services is a new blog post on the IoT channel. We understand the risks associated with operating at the edge and that you need additional capabilities to ensure that your data is protected. AWS IoT services can help you with end-to-end data protection, device security, and device identification to create the foundation of an expanded information security model and confidently operate at the edge.
AWS Open Source News and Updates – Ricardo Sueiras, my colleague from the AWS Developer Relation team, runs this newsletter. It brings you all the latest open-source projects, posts, and more. Read edition #113 here.
The AWS Summit season is mostly over in Europe, but there are upcoming Summits in North America and the Asia Pacific Regions. Here are some virtual and in-person Summits that might be close to you:
You can register for re:MARS to get fresh ideas on topics such as machine learning, automation, robotics, and space. The conference will be in person in Las Vegas, June 21–24.
That’s all for this week. Check back next Monday for another Week in Review!
AWS Service Catalog enables organizations to create and manage Information Technology (IT) services catalogs that are approved for use on AWS. These IT services can include resources such as virtual machine images, servers, software, and databases to complete multi-tier application architectures. AWS Service Catalog lets you centrally manage deployed IT services and your applications, resources, and metadata , which helps you achieve consistent governance and meet your compliance requirements. In addition, this configuration enables users to quickly deploy only approved IT services.
In large organizations, as more products are created, Service Catalog management can become exponentially complicated when different teams work on various products. The following solution simplifies Service Catalog products provisioning by considering elements such as shared accounts, roles, or users who can run portfolios or tags in the form of best practices via Continuous Integrations and Continuous Deployment (CI/CD) patterns.
This post demonstrates how Service Catalog Products can be delivered by taking advantage of the main benefits of CI/CD principles along with reducing complexity required to sync services. In this scenario, we have built a CI/CD Pipeline exclusively using AWS Services and the AWS Cloud Development Kit (CDK) Framework to provision the necessary Infrastructure.
Customers need the capability to consume services in a self-service manner, with services built on patterns that follow best practices, including focus areas such as compliance and security. The key tenants for these customers are: the use of infrastructure as code (IaC), and CI/CD. For these reasons, we built a scalable and automated deployment solution covered in this post.Furthermore, this post is also inspired from another post from the AWS community, Building a Continuous Delivery Pipeline for AWS Service Catalog.
Solution Overview
The solution is built using a unified AWS CodeCommit repository with CDK v1 code, which manages and deploys the Service Catalog Product estate. The solution supports the following scenarios: 1) making Products available to accounts and 2) provisioning these Products directly into accounts. The configuration provides flexibility regarding which components must be deployed in accounts as opposed to making a collection of these components available to account owners/users who can in turn build upon and provision them via sharing.
The pipeline created is comprised of the following stages:
Retrieving the code from the repository
Synthesize the CDK code to transform it into a CloudFormation template
Ensure the pipeline is defined correctly
Deploy and/or share the defined Portfolios and Products to a hub account or multiple accounts
Deploying and using the solution
Deploy the pipeline
We have created a Python AWS Cloud Development Kit (AWS CDK) v1 application hosted in a Git Repository. Deploying this application will create the required components described in this post. For a list of the deployment prerequisites, see the project README.
Clone the repository to your local machine. Then, bootstrap and deploy the CDK stack following the next steps.
The infrastructure creation takes around 3-5 minutes to complete deploying the AWS CodePipelines and repository creation. Once CDK has deployed the components, you will have a new empty repository where we will define the target Service Catalog estate. To do so, clone the new repository and push our sample code into it:
git clone https://git-codecommit.eu-west-1.amazonaws.com/v1/repos/service-catalog-repo
git checkout -b main
cd service-catalog-repo
cp -aR ../cdk-service-catalog-pipeline/* .
git add .
git commit -am "First commit"
git push origin main
Review and update configuration
Our cdk.json file is used to manage context settings such as shared accounts, permissions, region to deploy, etc.
shared_accounts_ecs: AWS account IDs where the ECS portfolio will be shared
shared_accounts_storage: AWS account IDs where the Storage portfolio will be shared
roles: ARN for the roles who will have permissions to access to the Portfolio
users: ARN for the users who will have permissions to access to the Portfolio
groups: ARN for the groups who will have permissions to access to the Portfolio
hub_account: AWS account ID where the Portfolio will be created
pipeline_account: AWS account ID where the main Infrastructure Pipeline will be created
region: the AWS region to be used for the deployment of the account
There are two mechanisms that can be used to create Service Catalog Products in this solution: 1) providing a CloudFormation template or 2) declaring a CDK stack (that will be transformed as part of the pipeline). Our sample contains two Products, each demonstrating one of these options: an Amazon Elastic Container Services (ECS) deployment and an Amazon Simple Storage Service (S3) product.
These Products are automatically shared with accounts specified in the shared_accounts_storage variable. Each product is managed by a CDK Python file in the cdk_service_catalog folder.
The Pipeline stages that AWS CodePipeline runs through are as follows:
Download the AWS CodeCommit code
Synthesize the CDK code to transform it into a CloudFormation template
Auto-modify the Pipeline in case you have made manual changes to it
Display the different Portfolios and Products associated in a Hub account in a Region or in multiple accounts
Adding new Portfolios and Products
To add a new Portfolio to the Pipeline, we recommend creating a new class under cdk_service_catalog similar to cdk_service_catalog_ecs_stack.py from our sample. Once the new class is created with the products you wish to associate, we instantiate the new class inside cdk_pipelines.py, and then add it inside the wave in the stage. There are two ways to create portfolio products. The first one is by creating a CloudFormation template, as can be seen in the Amazon Elastic Container Service (ECS) example. The second way is by creating a CDK stack that will be transformed into a template, as can be seen in the Storage example.
Product and Portfolio definition:
class ECSCluster(servicecatalog.ProductStack):
    def __init__(self, scope, id):
        super().__init__(scope, id)
        # Parameters for the Product Template
        cluster_name = cdk.CfnParameter(self, "clusterName", type="String", description="The name of the ECS cluster")
        container_insights_enable = cdk.CfnParameter(self, "container_insights", type="String",default="False",allowed_values=["False","True"],description="Enable Container Insights")
        vpc = cdk.CfnParameter(self, "vpc", type="AWS::EC2::VPC::Id", description="VPC")
        ecs.Cluster(self,"ECSCluster_template", enable_fargate_capacity_providers=True,cluster_name=cluster_name.value_as_string,container_insights=bool(container_insights_enable.value_as_string),vpc=vpc)
              cdk.Tags.of(self).add("key", "value")
Clean up
The following will help you clean up all necessary parts of this post: After completing your demo, feel free to delete your stack using the CDK CLI:
cdk destroy --all
Conclusion
In this post, we demonstrated how Service Catalog deployments can be accelerated by building a CI/CD pipeline using self-managed services. The Portfolio & Product estate is defined in its entirety by using Infrastructure-as-Code and automatically deployed based on your configuration. To learn more about AWS CDK Pipelines or AWS Service Catalog, visit the appropriate product documentation.
In part I of this series, we introduced a disaster recovery (DR) concept that uses managed services through a single AWS Region strategy. In part two, we introduce a multi-Region backup and restore approach. With this approach, you can deploy a DR solution in multiple Regions, but it will be associated with longer RPO/RTO. Using a backup and restore strategy will safeguard applications and data against large-scale events as a cost-effective solution, but will result in longer downtimes and greater loss of data in the event of a disaster as compared to other strategies as shown in Figure 1.
Figure 1. DR Strategies
Implementing the multi-Region/backup and restore strategy
Using multiple Regions ensures resiliency in the most serious, widespread outages. A secondary Region protects workloads against being unable to run within a given Region, because they are wide and geographically dispersed.
Architecture overview
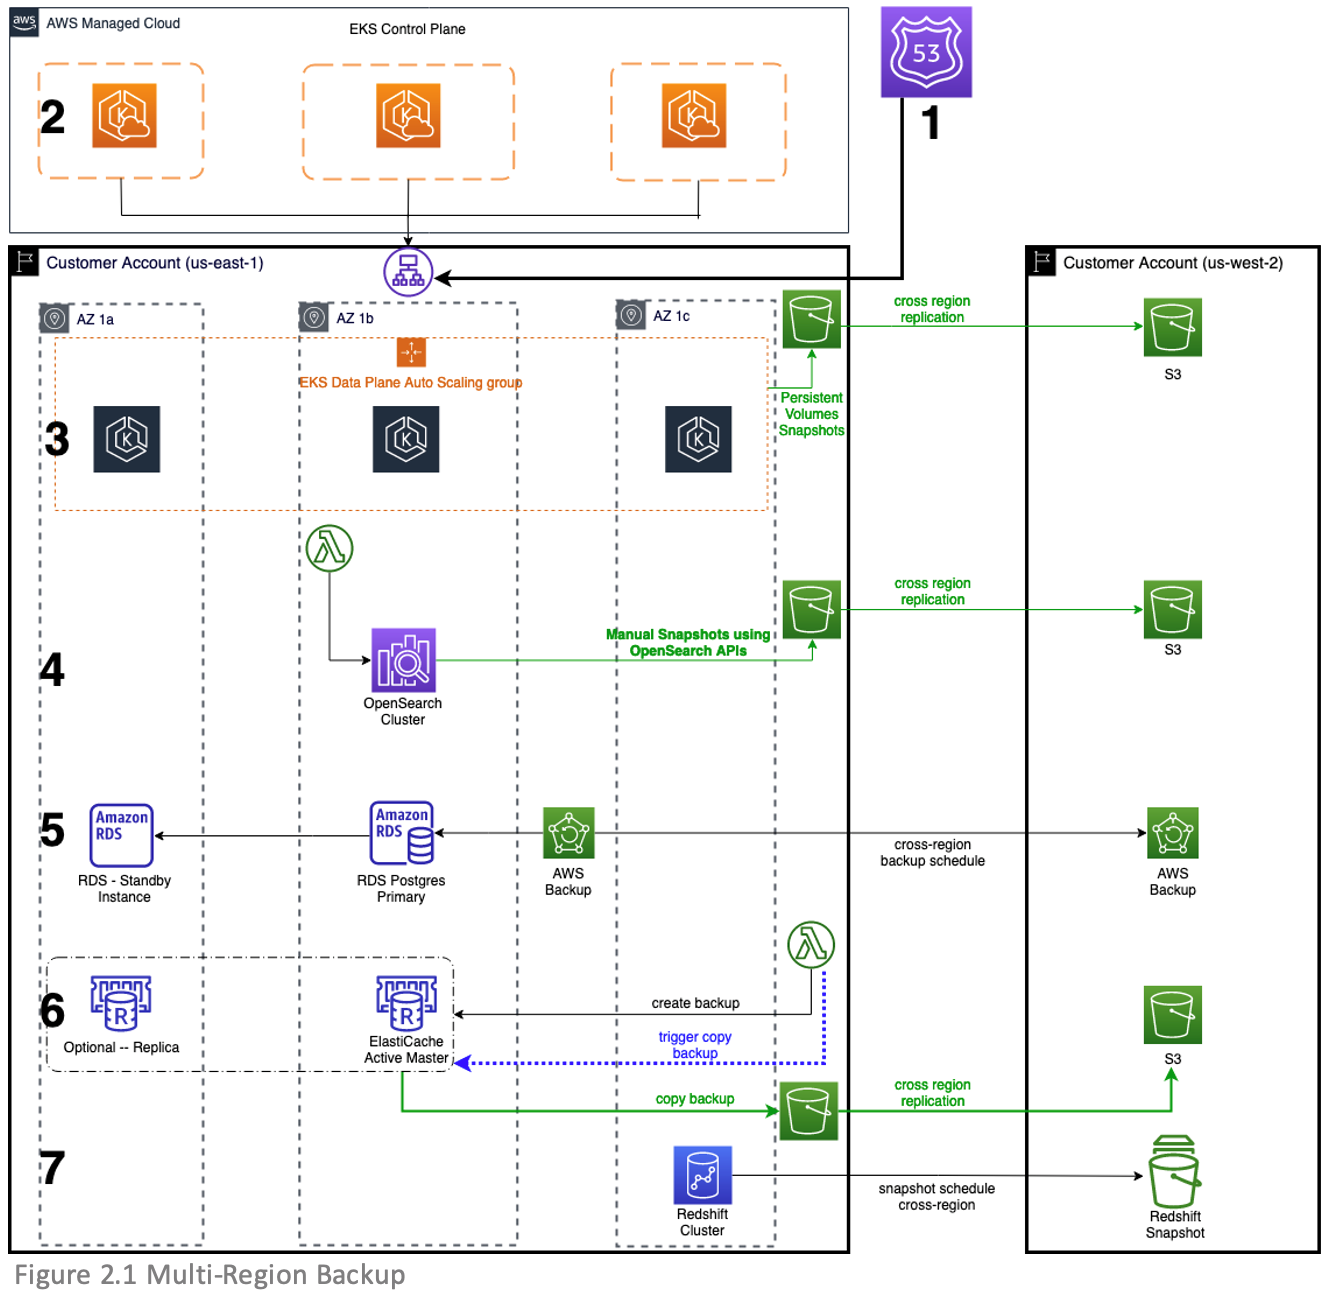
The application diagram presented in Figures 2.1 and 2.2 refers to an application that processes payment transactions, which was modernized to utilize managed services in the AWS Cloud. In this post, we’ll show you which AWS services it uses and how they work to maintain multi-Region/backup and restore strategy.
These figures show how to successfully implement the backup and restore strategy and successfully fail over your workload. The following sections list the components of the example application presented in the figures, which works as follows:
This SNS topic invokes an AWS Lambda function, which will invoke the infrastructure pipeline to initiate cluster provision in the secondary Region.
Figure 2.1. Multi-Region backup
Figure 2.2. Multi-Region restore
Route 53
Route 53 health checks monitor the health and performance of your web applications, web servers, and other resources. Health checks are necessary for configuring DNS failover within Route 53. Once an application or resource becomes unhealthy, you’ll need to initiate a manual failover process to create resources in the secondary Region. In our architecture, we use CloudWatch alarms to automate notifications of changes in health status.
Amazon Elastic Kubernetes Service (Amazon EKS) automatically scales control plane instances based on load, automatically detects and replaces unhealthy control plane instances, and restarts them across the Availability Zones within the Region as needed. Because on-demand clusters are provisioned in the secondary Region, AWS also manages the control plane the same way.
Amazon EKS data plane
It is a best practice to create worker nodes using Amazon Elastic Compute Cloud (Amazon EC2) Auto Scaling groups instead of creating individual EC2 instances and joining them to the cluster. This is because Amazon EC2 Auto Scaling groups automatically replace any terminated or failed nodes, which ensures that the cluster always has the capacity to run your workload.
The Amazon EKS control plane and data plane will be created on demand in the secondary Region during an outage via Infrastructure-as-a-Code (IaaC) such as AWS CloudFormation, Terraform, etc. You should pre-stage all networking requirements like virtual private cloud (VPC), subnets, route tables, gateways and deploy the Amazon EKS cluster during an outage in the primary Region.
During an outage in the primary Region, you can use the tool in the secondary Region to restore volumes from snapshots in the standby cluster.
OpenSearch Service
For domains running Amazon OpenSearch Service, OpenSearch Service takes hourly automated snapshots and retains up to 336 for 14 days. These snapshots can only be used for cluster recovery within the same Region as the primary OpenSearch cluster.
You can use OpenSearch APIs to create a manual snapshot of an OpenSearch cluster, which can be stored in a registered repository like Amazon S3. You can do this manually or create a scheduled Lambda function based on their RPO, which prompts creation of a manual snapshot that will be stored in an S3 bucket. Amazon S3 cross-Region replication will then automatically and asynchronously copy objects across S3 buckets.
You can restore OpenSearch Service clusters by creating the cluster on demand via CloudFormation and using OpenSearch APIs to restore the snapshot from an S3 bucket.
Amazon RDS Postgres
Amazon Relational Database Service (Amazon RDS) can copy continuous backups cross-Region. You can configure your Amazon RDS database instance to replicate snapshots and transaction logs to a destination Region of your choice.
If a continuous backup rule also specifies a cross-account or cross-Region copy, AWS Backup takes a snapshot of the continuous backup, copies that snapshot to the destination vault, and then deletes the source snapshot. For continuous backup of Amazon RDS, AWS Backup creates a snapshot every 24 hours and stores transaction logs every 5 minutes in-Region. The Backup Frequency setting only applies to cross-Region backups of these continuous backups. Backup Frequency determines how often AWS Backup:
Creates a snapshot at that point in time from the existing snapshot plus all transaction logs up to that point
Copies snapshots to the other Region(s)
Deletes snapshots (because it only was created to be copied)
You can export and import backup and copy API calls for Amazon ElastiCache to develop a snapshot and restore strategy in a secondary Region. You can either prompt a manual backup and copy of that backup to S3 bucket or create a pair of Lambda functions to run at a schedule to meet the RPO requirements. The Lambda functions will prompt a manual backup, which creates a .rdb to an S3 bucket. Amazon S3 cross-Region replication will then handle asynchronous copy of the backup to an S3 bucket in a secondary Region.
You can use CloudFormation to create an ElastiCache cluster on demand and use CloudFormation properties such as SnapshotArns and SnapshotName to point to the desired ElastiCache backup stored in Amazon S3 to seed the cluster in the secondary Region.
Amazon Redshift
Amazon Redshift takes automatic, incremental snapshots of your data periodically and saves them to Amazon S3. Additionally, you can take manual snapshots of your data whenever you want.
To precisely control when snapshots are taken, you can create a snapshot schedule and attach it to one or more clusters. You can also configure cross-Region snapshot copy, which will automatically copy all your automated and manual snapshots to another Region.
During an outage, you can create the Amazon Redshift cluster on demand via CloudFormation and use CloudFormation properties such as SnapshotIdentifier to restore the new cluster from that snapshot.
With greater adoption of managed services within the cloud, there is a need to think of creative ways to implement a cost-effective DR solution. This backup and restore approach offered in this post will lower costs through more lenient RPO/RTO requirements, while providing a solution to utilize AWS managed services.
In the next post, we will discuss a multi-Region active/active strategy for the same application stack illustrated in this post.
Looking for more architecture content?AWS Architecture Center provides reference architecture diagrams, vetted architecture solutions, Well-Architected best practices, patterns, icons, and more!
Не е лесно да си извадиш главата от гъза. Ще дам личен пример. Близо пет петилетки залагах. Печелех, губех, въртях се в омагьосан кръг. Никога не можеш да победиш казиното.…
Amazon QuickSight is a scalable, serverless, embeddable, machine learning (ML)-powered business intelligence (BI) service built for the cloud that supports identity federation in both Standard and Enterprise editions. Organizations are working towards centralizing their identity and access strategy across all of their applications, including on-premises, third-party, and applications on AWS. Many organizations use Google Workspace to control and manage user authentication and authorization centrally. You can enable federation to QuickSight accounts without needing to create and manage users. This authorizes users to access QuickSight assets—analyses, dashboards, folders, and datasets—through centrally managed Google Workspace Identities.
In this post, we go through the steps to configure federated single sign-on (SSO) between a Google Workspace instance and QuickSight account. We demonstrate registering an SSO application in Google Workspace, and map QuickSight roles (admin, author, and reader) to Google Workspace Identities. These QuickSight roles represent three different personas supported in QuickSight. Administrators can publish the QuickSight app in a Google Workspace Dashboard to enable users to SSO to QuickSight using their Google Workspace credentials.
Solution overview
In your organization, the portal is typically a function of your identity provider (IdP), which handles the exchange of trust between your organization and QuickSight.
On the Google Workspace Dashboard, you can review a list of apps. This post shows you how to configure the custom app for AWS.
The user flow consists of the following steps:
The user logs in to your organization’s portal and chooses the option to go to the QuickSight console.
The portal verifies the user’s identity in your organization.
The portal generates a SAML authentication response that includes assertions that identify the user and include attributes about the user. The portal sends this response to the client browser. Although not discussed here, you can also configure your IdP to include a SAML assertion attribute called SessionDuration that specifies how long the console session is valid.
The client browser is redirected to the AWS single sign-on endpoint and posts the SAML assertion.
The endpoint requests temporary security credentials on behalf of the user, and creates a QuickSight sign-in URL that uses those credentials.
AWS sends the sign-in URL back to the client as a redirect.
The client browser is redirected to the QuickSight console. If the SAML authentication response includes attributes that map to multiple AWS Identity and Access Management (IAM) roles, the user is first prompted to select the role for accessing the console.
The following diagram illustrates the solution architecture.
The following are the high-level steps to set up federated single sign-on access via Google Workspace:
Download the Google IdP information.
Create an IAM IdP with Google as SAML IdP.
Configure IAM policies for QuickSight roles.
Configure IAM QuickSight roles for federated users.
Create a custom user attribute in Google Workspace.
Add the AWS SAML attributes to your Google Workspace user profile.
Set up the AWS SAML app in Google Workspace.
Grant access to users in Google Workspace.
Verify federated access to your QuickSight instance.
Detailed procedures for each of these steps comprise the remainder of this post.
Prerequisites
For this walkthrough, you should have the following prerequisites:
Basic understanding of QuickSight roles—admin, author, and reader
Basic understanding of IAM and privileges required to create an IAM identity provider, roles, policies, and users
Download the Google IdP information
First, let’s get the SAML metadata that contains essential information to enable your AWS account to authenticate the IdP and locate the necessary communication endpoint locations. Complete the following steps:
Create a custom user attribute in Google Workspace
Now let’s create a custom user attribute in your Google Workspace. This allows us to add the SAML attributes that the AWS Management Console expects in order to allow a SAML-based authentication.
Choose the user’s name to open their account page.
Choose User information.
Choose custom attribute you recently created, named Amazon.
Add a value to this custom attribute noted earlier in the following format: <AWS Role ARN>,<AWS provider/IdP ARN>.
Choose Save.
Set up the AWS SAML app in Google Workspace
Now that we have everything in place, we’re ready to create a SAML app within our Google Workspace account and provide the QuickSight instance starting URL. This provides the entry point for Google Workspace users to SSO into the QuickSight instance.
While logged in to Google Admin console with admin credentials, under Apps, choose Web and mobile apps.
Choose Add App, and Search for apps.
Enter Amazon Web Services in the search field.
In the search results, hover over the Amazon Web Services SAML app and choose Select.
On the Google Identity Provider details page, choose Continue.
On the Service provider details page, the ACS URL and Entity ID values for Amazon Web Services are configured by default.
For Start URL, enter https://quicksight.aws.amazon.com.
On the Attribute Mapping page, choose the Select field menu and map the following Google directory attributes to their corresponding Amazon Web Services attributes:
When the SAML app is created in Google workspace, it’s turned off by default. This means for users logged in to their Google Workspace account, the SAML app isn’t visible to them. We now enable the AWS SAML app to your Google Workspace users.
While logged in to the Google Admin console with admin credentials, navigate to the Web and mobile apps page.
Choose Amazon Web Services.
Choose User access.
To turn on a service for everyone in your organization, choose ON for everyone.
Choose Save.
If you don’t want to activate this application for all users, you can alternatively grant access to a subset of users by using Google Workspace organizational units.
Verify federated access to the QuickSight instance
To test your SAML 2.0-based authentication with QuickSight for users in your existing IDP (Google Workspace), complete the following steps:
Open a new browser session, for example, using Chrome, in a new incognito window.
Log in to your Google Workspace account (for the purpose of this demo, we use the Google Workspace admin account).
Choose Amazon Web Services from the list of Google apps.
Conclusion
This post provided a step-by-step guide for configuring Google Workspace as your IdP, and using IAM roles to enable SSO to QuickSight. Now your users have a seamless sign-in experience to QuickSight and have the appropriate level of access related to their role.
To get answers to your questions related to QuickSight, refer to the QuickSight Community.
If you have any questions or feedback, please leave a comment.
About the Authors
Sriharsh Adari is a Senior Solutions Architect at Amazon Web Services (AWS), where he helps customers work backwards from business outcomes to develop innovative solutions on AWS. Over the years, he has helped multiple customers on data platform transformations across industry verticals. His core area of expertise include Technology Strategy, Data Analytics, and Data Science. In his spare time, he enjoys playing sports, binge-watching TV shows, and playing Tabla.
Srikanth Baheti is a Specialized World Wide Sr. Solution Architect for Amazon QuickSight. He started his career as a consultant and worked for multiple private and government organizations. Later he worked for PerkinElmer Health and Sciences & eResearch Technology Inc, where he was responsible for designing and developing high traffic web applications, highly scalable and maintainable data pipelines for reporting platforms using AWS services and Serverless computing.
The 5.18 kernel was released
on May 22 after a nine-week development cycle. That can only mean
that the time has come to look at some of the statistics behind this
release, which was one of the busiest in a while. Read on for a look at
the 5.18 kernel, where the code in this release came from, and how it found
its way into the mainline.
When that breach happens, you’ll most likely need help. For Rapid7 MDR customers, we’re there for you when you need us, period. Our belief is that, if a breach is inevitable, then a logical, transparent, collaborative, and effective approach to response should be, too.
I’m not just talking about the table-stakes “response” to everyday security threats. I’m talking about digital forensics and world-class incident response for any incident – no matter if it’s a minor breach like a phishing email with an attached maldoc or a major targeted breach involving multiple endpoints compromised by an advanced attacker.
Protecting your environment is our shared responsibility. As long as you are willing and able to partner with us during and after the Incident Response process, we are here for you. Rapid7 does the DFIR heavy lift. You cooperate to eradicate the threat and work to improve your security posture as a result.
Unfortunately, that’s not how all of the market sees it.
How vendors typically provide DFIR
Some managed detection and response (MDR) vendors or managed security services providers (MSSPs) do understand that there’s an R in MDR. Typically, they’ll do a cursory investigation, validation and – if you’re lucky – some form of basic or automated response.
For most, that’s where the R stops. If they can’t handle an emergency breach response situation (or if you’re on your own without any DFIR on staff), you’ll wind up hiring a third-party incident response (IR) consulting service. This will be a service you’ve found, or one that’s required by your cyber insurance provider. Perhaps you planned ahead and pre-purchased an hourly IR retainer.
Either way, how you pay for IR determines your customer experience during “response.” It’s a model designed to maximize provider profits, not your outcomes.
At a glance
IR Consulting Services
IR Included in Managed Services
Scope
Unbounded
Limited to managed services in-scope environments
Time Limit
Capped by number of hours or number of incidents
Capped by number of hours or number of incidents
Expertise
Senior IR Consultants
Capped by number of hours or number of incidents
24×7 IR
No
Yes
Tooling
Often will deploy a separate tooling stack, without easy access to historical data
Existing tooling, utilizing historical data but potentially lacking in forensic capability
Time to Respond
Slower (limited by legal documents, SLAs, lack of familiarity in the customer environment, time for tool deployment)
Proactively purchased as a retainer or reactively on an hourly basis
Included in purchase, up to an arbitrarily defined limit
There’s a good reason DFIR experts are reserved for expensive consulting services engagements. They’re a rare breed.
Most MDR teams can’t afford to staff the same DFIR experts that answer the Breach Response hotline. Security vendors price, package, and deliver these services in a way to reserve their more experienced (and expensive) experts for IR consulting.
Either you purchase Managed Services and expensive IR consulting hours (and play intermediary between these two separate teams), or you settle for “Incident Response lite” from your Managed Services SOC team.
If this seems like a “lesser of two evils” approach with two unappealing options, it is.
The future of incident response has arrived
Over a year ago, Rapid7 merged our Incident Response Consulting Team with our MDR SOC to ensure all MDR customers receive the same high-caliber DFIR expertise as a core capability of our service – no Breach Response hotlines or retainer hours needed.
This single, integrated team of Detection and Response experts started working together to execute on our response mission: early detection and rapid, highly effective investigation, containment, and eradication of threats.
Our SOC analysts are experts on alert triage, tuning, and threat hunting. They have the most up-to-date knowledge of attackers’ current tactics, techniques, and procedures and are extremely well-versed in attacker behavior, isolating malicious activity and stopping it in its tracks. When a minor incident is detected, our SOC analysts begin incident investigation – root cause analysis, malware reverse engineering, malicous code deobfuscation, and more – and response immediately. If the scope becomes large and complex, we (literally) swivel our chair to tap our IR reinforcements on the shoulder.
Senior IR consultants are seasoned DFIR practitioners. They’re also the experts leading the response to major breaches, directing investigation, containment, and eradication activities while clearly communicating with stakeholders on the status, scope, and impact of the incident.
Both teams benefit. The managed services SOC team has access to a world class Incident Response team. And the expert incident response consultants have a global team of (also world class) security analysts trained to assist with forensic investigation and response around the clock (including monitoring the compromised environment for new attacker activity).
Most importantly, our MDR customers benefit. This reimagining of how we work together delivers seamless, effective incident response for all. When every second counts, an organization cannot afford the limited response of most MDR providers, or the delay and confusion that comes with engaging a separate IR vendor.
Grab a coffee, it’s major breach story time
Here’s a real-life example of how our integrated approach works.
In early January, a new MDR client was finishing the onboarding process by installing the Insight Agent on their devices. Almost immediately upon agent installation, the MDR team noticed critical alerts flowing into InsightIDR (our unified SIEM and XDR solution).
Our SOC analysts dug in and realized this wasn’t a typical attack. The detections indicated a potential major incident, consistent with attacker behavior for ransomware. SOC analysts immediately used Active Response to quarantine the affected assets and initiated our incident response process.
The investigation transitioned to the IR team within minutes, and a senior IR consultant (from the same team responsible for leading breach response for Rapid7’s off-the-street or retainer customers) took ownership of the incident response engagement.
After assessing the early information provided by the SOC, the IR consultant identified the highest-priority investigation and response actions, taking on some of these tasks directly and assigning other tasks to additional IR consultants and SOC analysts. The objective: teamwork and speed.
The SOC worked around the clock together with the IR team to search these systems and identify traces of malicious activity. The team used already-deployed tools, such as InsightIDR and Velociraptor (Rapid7’s open-source DFIR tool).
This major incident was remediated and closed within three days of the initial alert, stopping the installation of ransomware within the customer’s environment and cutting out days and even weeks of back-and-forth between the customer, the MDR SOC team, and a third-party Breach Response team.
Now, no limits and a customer experience you’ll love
The results speak for themselves. Not only does the embedded IR model enable each team to reach beyond its traditional boundaries, it brings faster and smoother outcomes to our customers.
And now we’re taking this a step further.
Previously, our MDR services included up to two “uncapped” (no limit on IR team time and resources) Remote Incident Response engagements per year. While this was more than enough for most customers (and highly unusual for an MDR provider), we realized that imposing any arbitrary limits on DFIR put unnecessary constraints on delivering on our core mission.
For this reason, we have removed the Remote Incident Response limits from our MDR service across all tiers. Rapid7 will now respond to ALL incidents within our MDR customers’ in-scope environments, regardless of incident scope and complexity, and bring all the necessary resources to bear to effectively investigate, contain and eradicate these threats.
Making these DFIR engagements – often reserved for breach response retainer customers – part of the core MDR service (not just providing basic response or including hours for a retainer) just raised the “best practices” bar for the industry.
It’s not quite unlimited, but it’s close. The way we see it, we’ll assist with the hard parts of DFIR, while you partner with us to eradicate the threat and implement corrective actions. That partnership is key: Implementing required remediation, mitigation, and corrective actions will help to reduce the likelihood of incident recurrence and improve your overall security posture.
After all, that’s what MDR is all about.
P.S.: If you’re a security analyst or incident responder, we’re hiring!
In addition to providing world-class breach response services to our MDR customers, this new approach makes Rapid7 a great place to work and develop new skills.
Our SOC analysts develop their breach response expertise by working shoulder-to-shoulder with our Incident Response team. And our IR team focuses on doing what they love – not filling out time cards and stressing over their “utilization” as consultants, but leading the response to complex, high-impact breaches and being there for our customers when they need us the most. Plus, with the support and backing of a global SOC, our IR team can actually sleep at night!
Despite the worldwide cybersecurity skills crisis and The Great Resignation sweeping the industry, Rapid7’s MDR team grew by 30% last year with only 5% voluntary analyst turnover – in line with our last three years.
Part of this exceptionally low turnover is due to:
Investment in continuing education, diversity, and employee retention benefits
A robust training program, clear career progression, the opportunity to level up skills by teaming with IR mentors, and flexibility for extra-curricular “passion project” work (to automate processes and improve aspects of MDR services)
Competitive pay, and a focus on making sure analysts are doing work they enjoy day in and day out with a healthy work-life balance (there’s no such thing as a “night shift” since we use a follow-the-sun SOC model)
If you’re a Security Analyst or Incident Responder looking for a new challenge, come join our herd. I think Jeremiah Dewey, VP of Rapid7’s Managed Services, said it best:
“Work doesn’t have to be a soul-sucking, boring march to each Friday. You can follow your passion, have fun in what you’re doing, and be successful in growing your career and growing as a human being.”
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.