Post Syndicated from Explosm.net original https://explosm.net/comics/come-inside
New Cyanide and Happiness Comic
Post Syndicated from Explosm.net original https://explosm.net/comics/come-inside
New Cyanide and Happiness Comic
Post Syndicated from Oglaf! -- Comics. Often dirty. original https://www.oglaf.com/goat/

Post Syndicated from Will Matos original https://aws.amazon.com/blogs/devops/building-with-ai-dlc-using-amazon-q-developer/
The AI-Driven Development Life Cycle (AI-DLC) methodology marks a significant change in software development by strategically assigning routine tasks to AI while maintaining human oversight for critical decisions. Amazon Q Developer, a generative AI coding assistant, supports the entire software development lifecycle and offers the Project Rules feature, allowing users to tailor their development practices within the platform.
Recently, AWS made its AI-DLC workflow open-source, enabling developers to create software using this methodology. This workflow is implemented in Amazon Q Developer through its Project Rules customization feature. In this post, we will demonstrate how the AI-DLC workflow operates in Amazon Q Developer using an example use case.
The AI-DLC workflow is the practical implementation of the AI-DLC methodology for executing software development tasks. As outlined in the AI-DLC Method Definition Paper, the workflow has three phases. These phases are Inception, Construction, and Operations. Inception involves planning and architecture. Construction focuses on design and implementation. Operations cover deployment and monitoring. Each phase includes distinct stages. These stages address specific software development life cycle functions. The workflow adapts to project requirements. It analyzes requests, codebases, and complexity. This analysis determines the necessary stages. Simple bug fixes skip planning. They go directly to code generation. Complex features need requirements analysis. They also require architectural design and detailed testing.
The workflow maintains quality and control through structured milestones and transparent decision-making. At each phase, AI-DLC asks clarifying questions, creates execution plans, and waits for approval. Every decision, input, and response is logged in an audit trail for traceability. Whether building a new microservice, refactoring legacy code, or fixing a production bug, AI-DLC scales its rigor to match needs—comprehensive when complex, efficient when simple, and always in control. Figure 1 shows the phases and stages within the adaptive AI-DLC workflow. The stages shown in green boxes are mandatory, while those in yellow boxes are conditional.
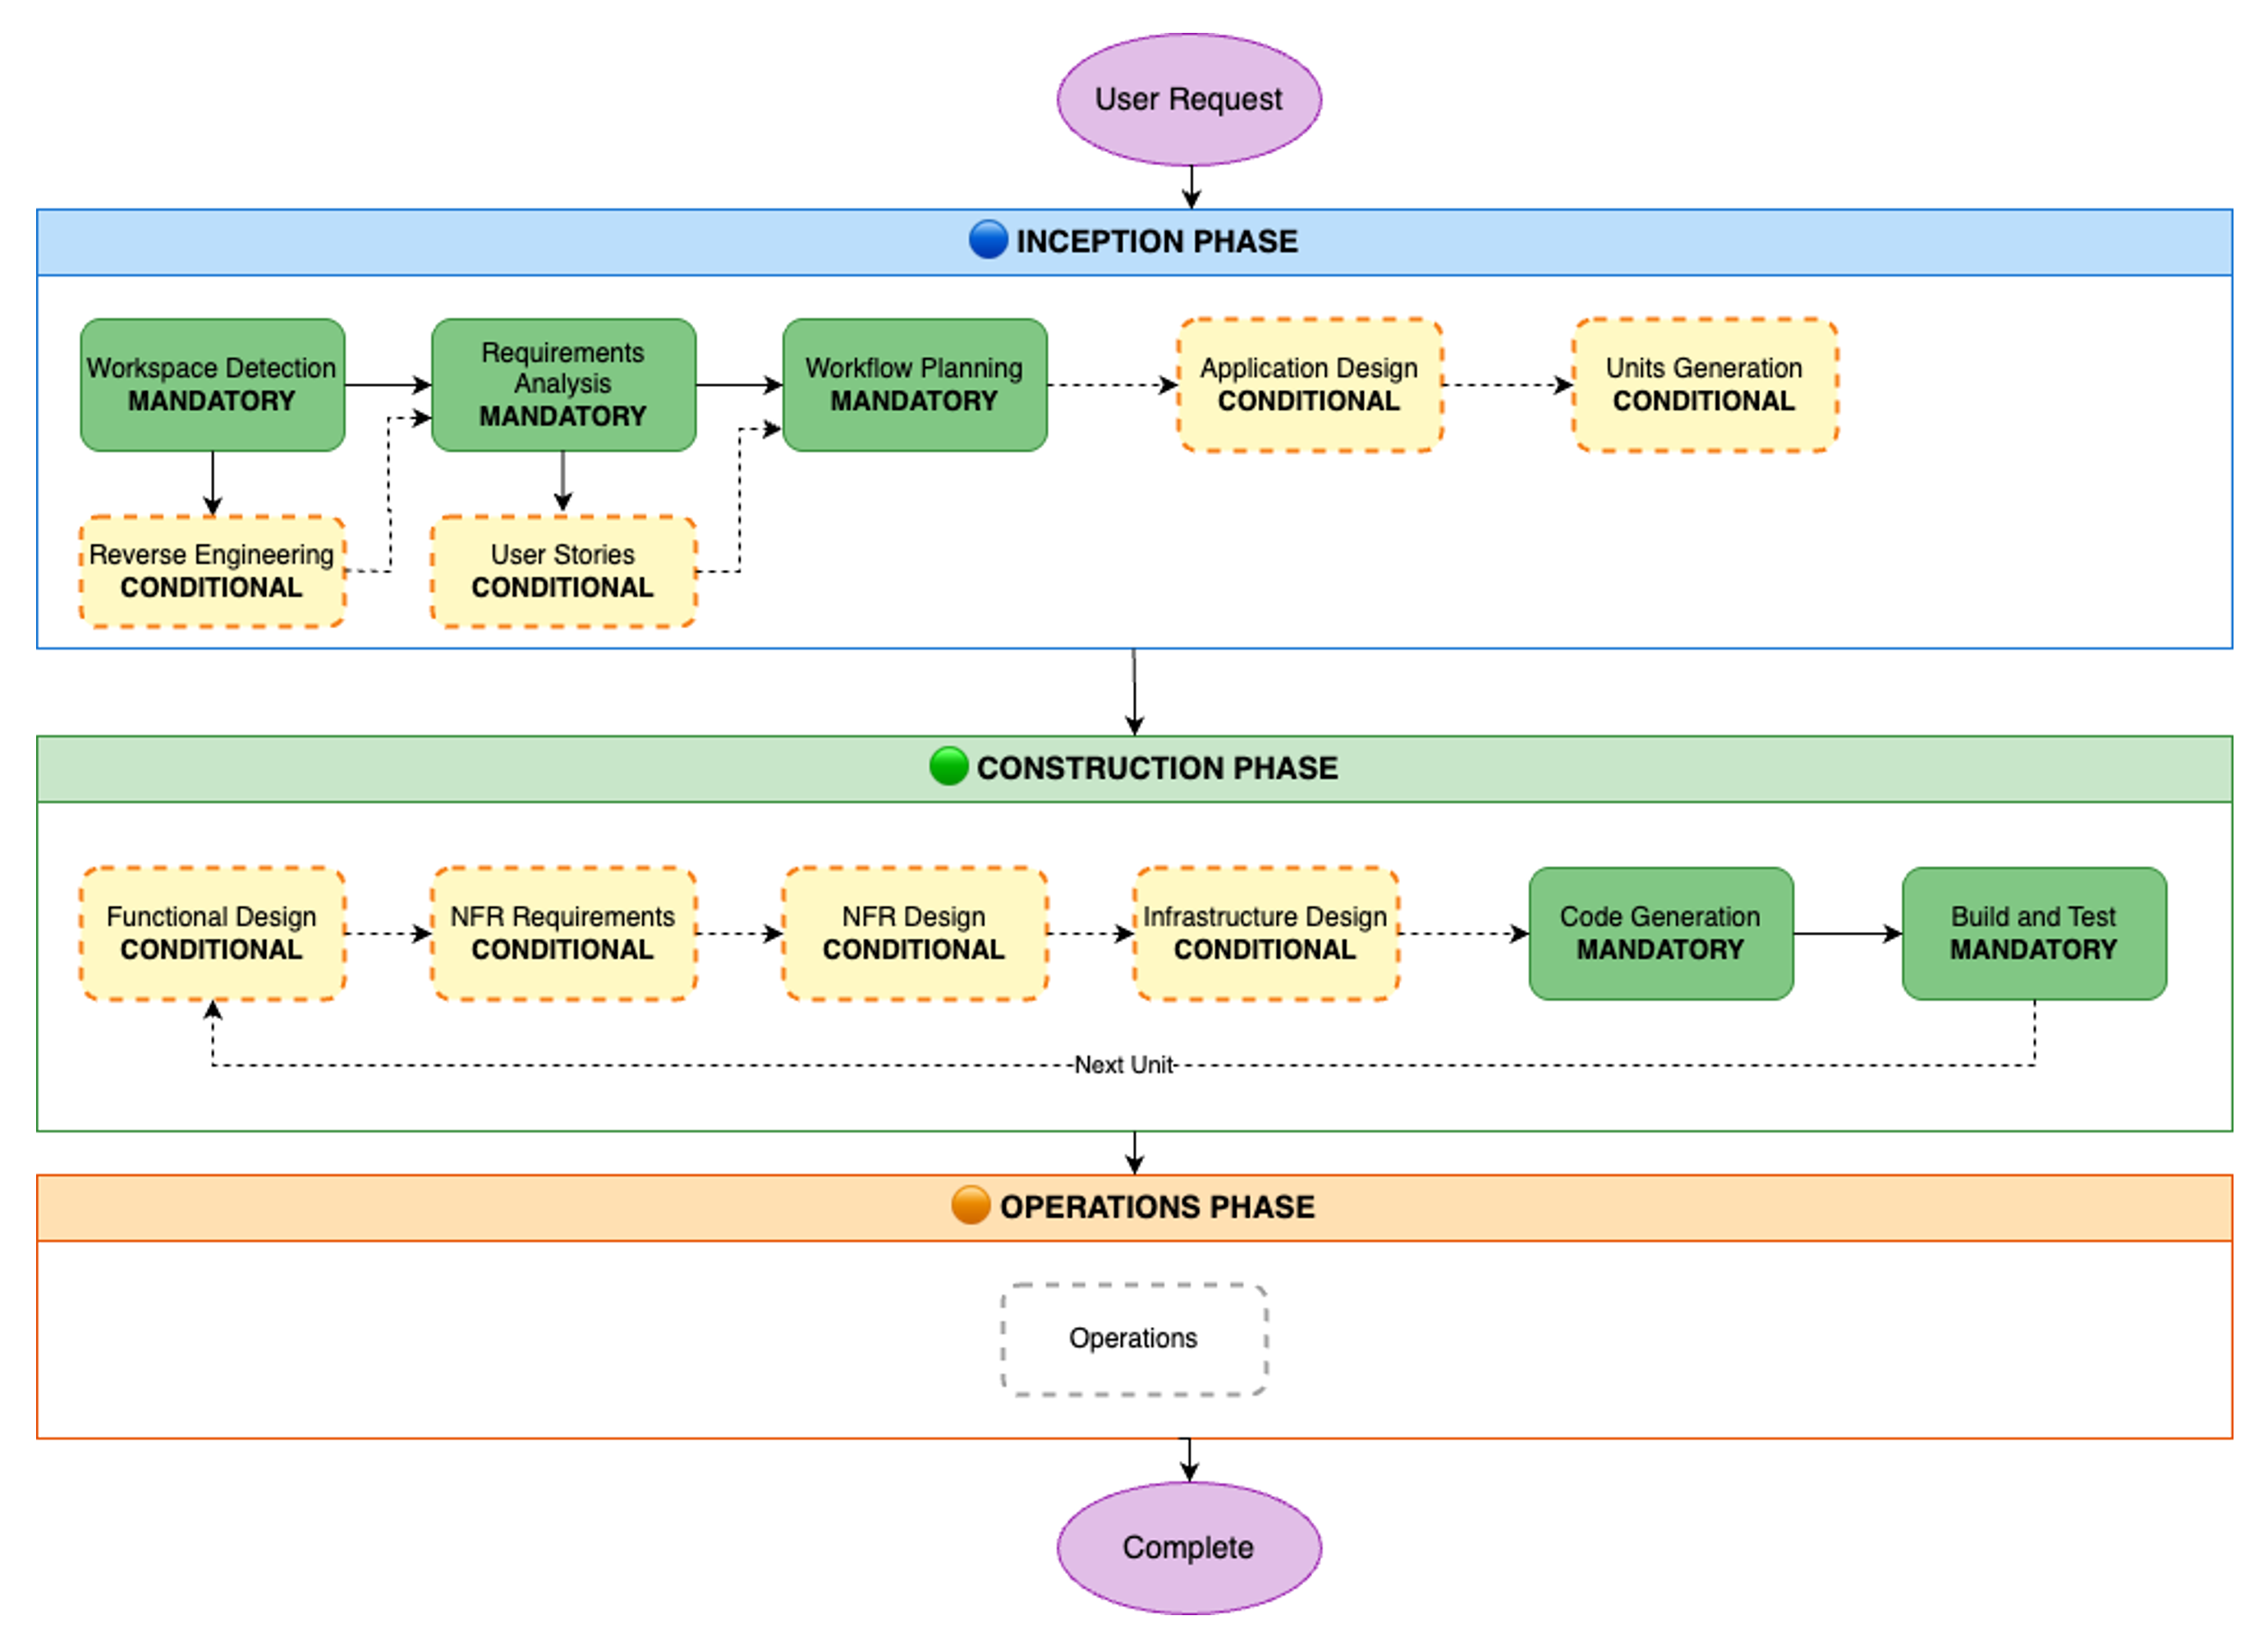
Figure 1. SDLC phases and stages in AI-DLC workflow
Before we begin the walk-through, we must have an AWS account or AWS Builder Id for authenticating Amazon Q Developer. If you don’t have one, sign up for AWS account or create an AWS builder id. You can use any of the Integrated Development Environments (IDEs) supported by Amazon Q Developer and install the extension as per the AWS documentation. In this post, we’ll be using the Amazon Q Developer extension in VS Code IDE. Once the plug-in is installed, you’ll need to authenticate Q Developer with the AWS cloud backend. Refer to the AWS documentation for Q Developer authentication instructions.
The AI-DLC workflow generates various Mermaid diagrams in markdown files. To view these diagrams within your IDE, you can install a Mermaid viewer plugin.
Let’s construct a simple River Crossing Puzzle as a web UI app using AI-DLC. By choosing a straightforward app, we can concentrate more on learning the AI-DLC workflow and less on the project’s technical intricacies.
The sections below outline the individual steps in the AI-DLC development process using Amazon Q Developer. We’ll showcase screenshots of our IDE with the Amazon Q Developer plug-in and demonstrate how to interact with the workflow.
Although we’ve used the Amazon Q Developer IDE plug-in in this blog post, you can also use Kiro Command Line Interface (CLI) to build with AI-DLC without any additional setup. The workflow remains the same, except that you’ll interact through the command line instead of the graphical interface in the IDE.
Clone the GitHub repo containing the AI-DLC Q Developer Rules:
git clone https://github.com/awslabs/aidlc-workflows.gitFollow the README.md instructions in the GitHub repo to copy the rules files over to your project folder.
Open the project folder you created in Step 2 in VS Code. Open the Amazon Q Chat Panel in the IDE and ensure that the AI-DLC workflow rules are loaded in Q Developer, as shown in Figure 2. If you don’t see what’s shown in Figure 2, please double-check the steps you performed in Step 2.

Figure 2: AI-DLC rules enabling in Amazon Q Developer
Our development environment is now set up, and we’re ready to begin application development using AI-DLC. In our Q Developer chat session, we enter the following problem statement:
Notice that we’ve prefixed our problem statement with “Using AI-DLC …” to ensure that Q Developer engages the AI-DLC workflow. Figure 3 shows what happens next. The AI-DLC workflow is triggered within Q Developer. It greets us with a welcome message and provides a brief overview of the AI-DLC methodology.
Figure 3 shows an expanded view of the AI-DLC workflow rules folder structure on the left. You’ll notice that a single aws-aidlc-rules/core-workflow.md is placed in the designated .amazonq/rules folder, while the rest of the rules files are placed in an ordinary aws-aidlc-rule-details folder. This arrangement is designed to optimize model efficiency. By placing the aws-aidlc-rules/core-workflow.md file in the .amazonq/rules folder, , it serves as additional context, ensuring that the core workflow structure is always accessible without incurring additional token consumption. Conversely, the detailed phase and stage-level behavior rules are stored in the aws-aidlc-rule-details folder and are dynamically loaded as required. This approach conserves Amazon Q’s context window and token usage by retaining only the necessary information within the context at any given time, thereby enhancing model efficiency.
The rules files under the aws-aidlc-rule-details folder are organized into three sub-folders, each representing a phase of AI-DLC. Within each phase, there are stage-specific files. A common folder houses cross-cutting rules applicable to all AI-DLC phases and stages such as the “human-in-the-loop”.
The AI-DLC workflow is self-guided and provides us with a clear understanding of what to expect next. It informs us that it will enter the AI-DLC Inception phase next, starting with the Workspace Detection stage within it.
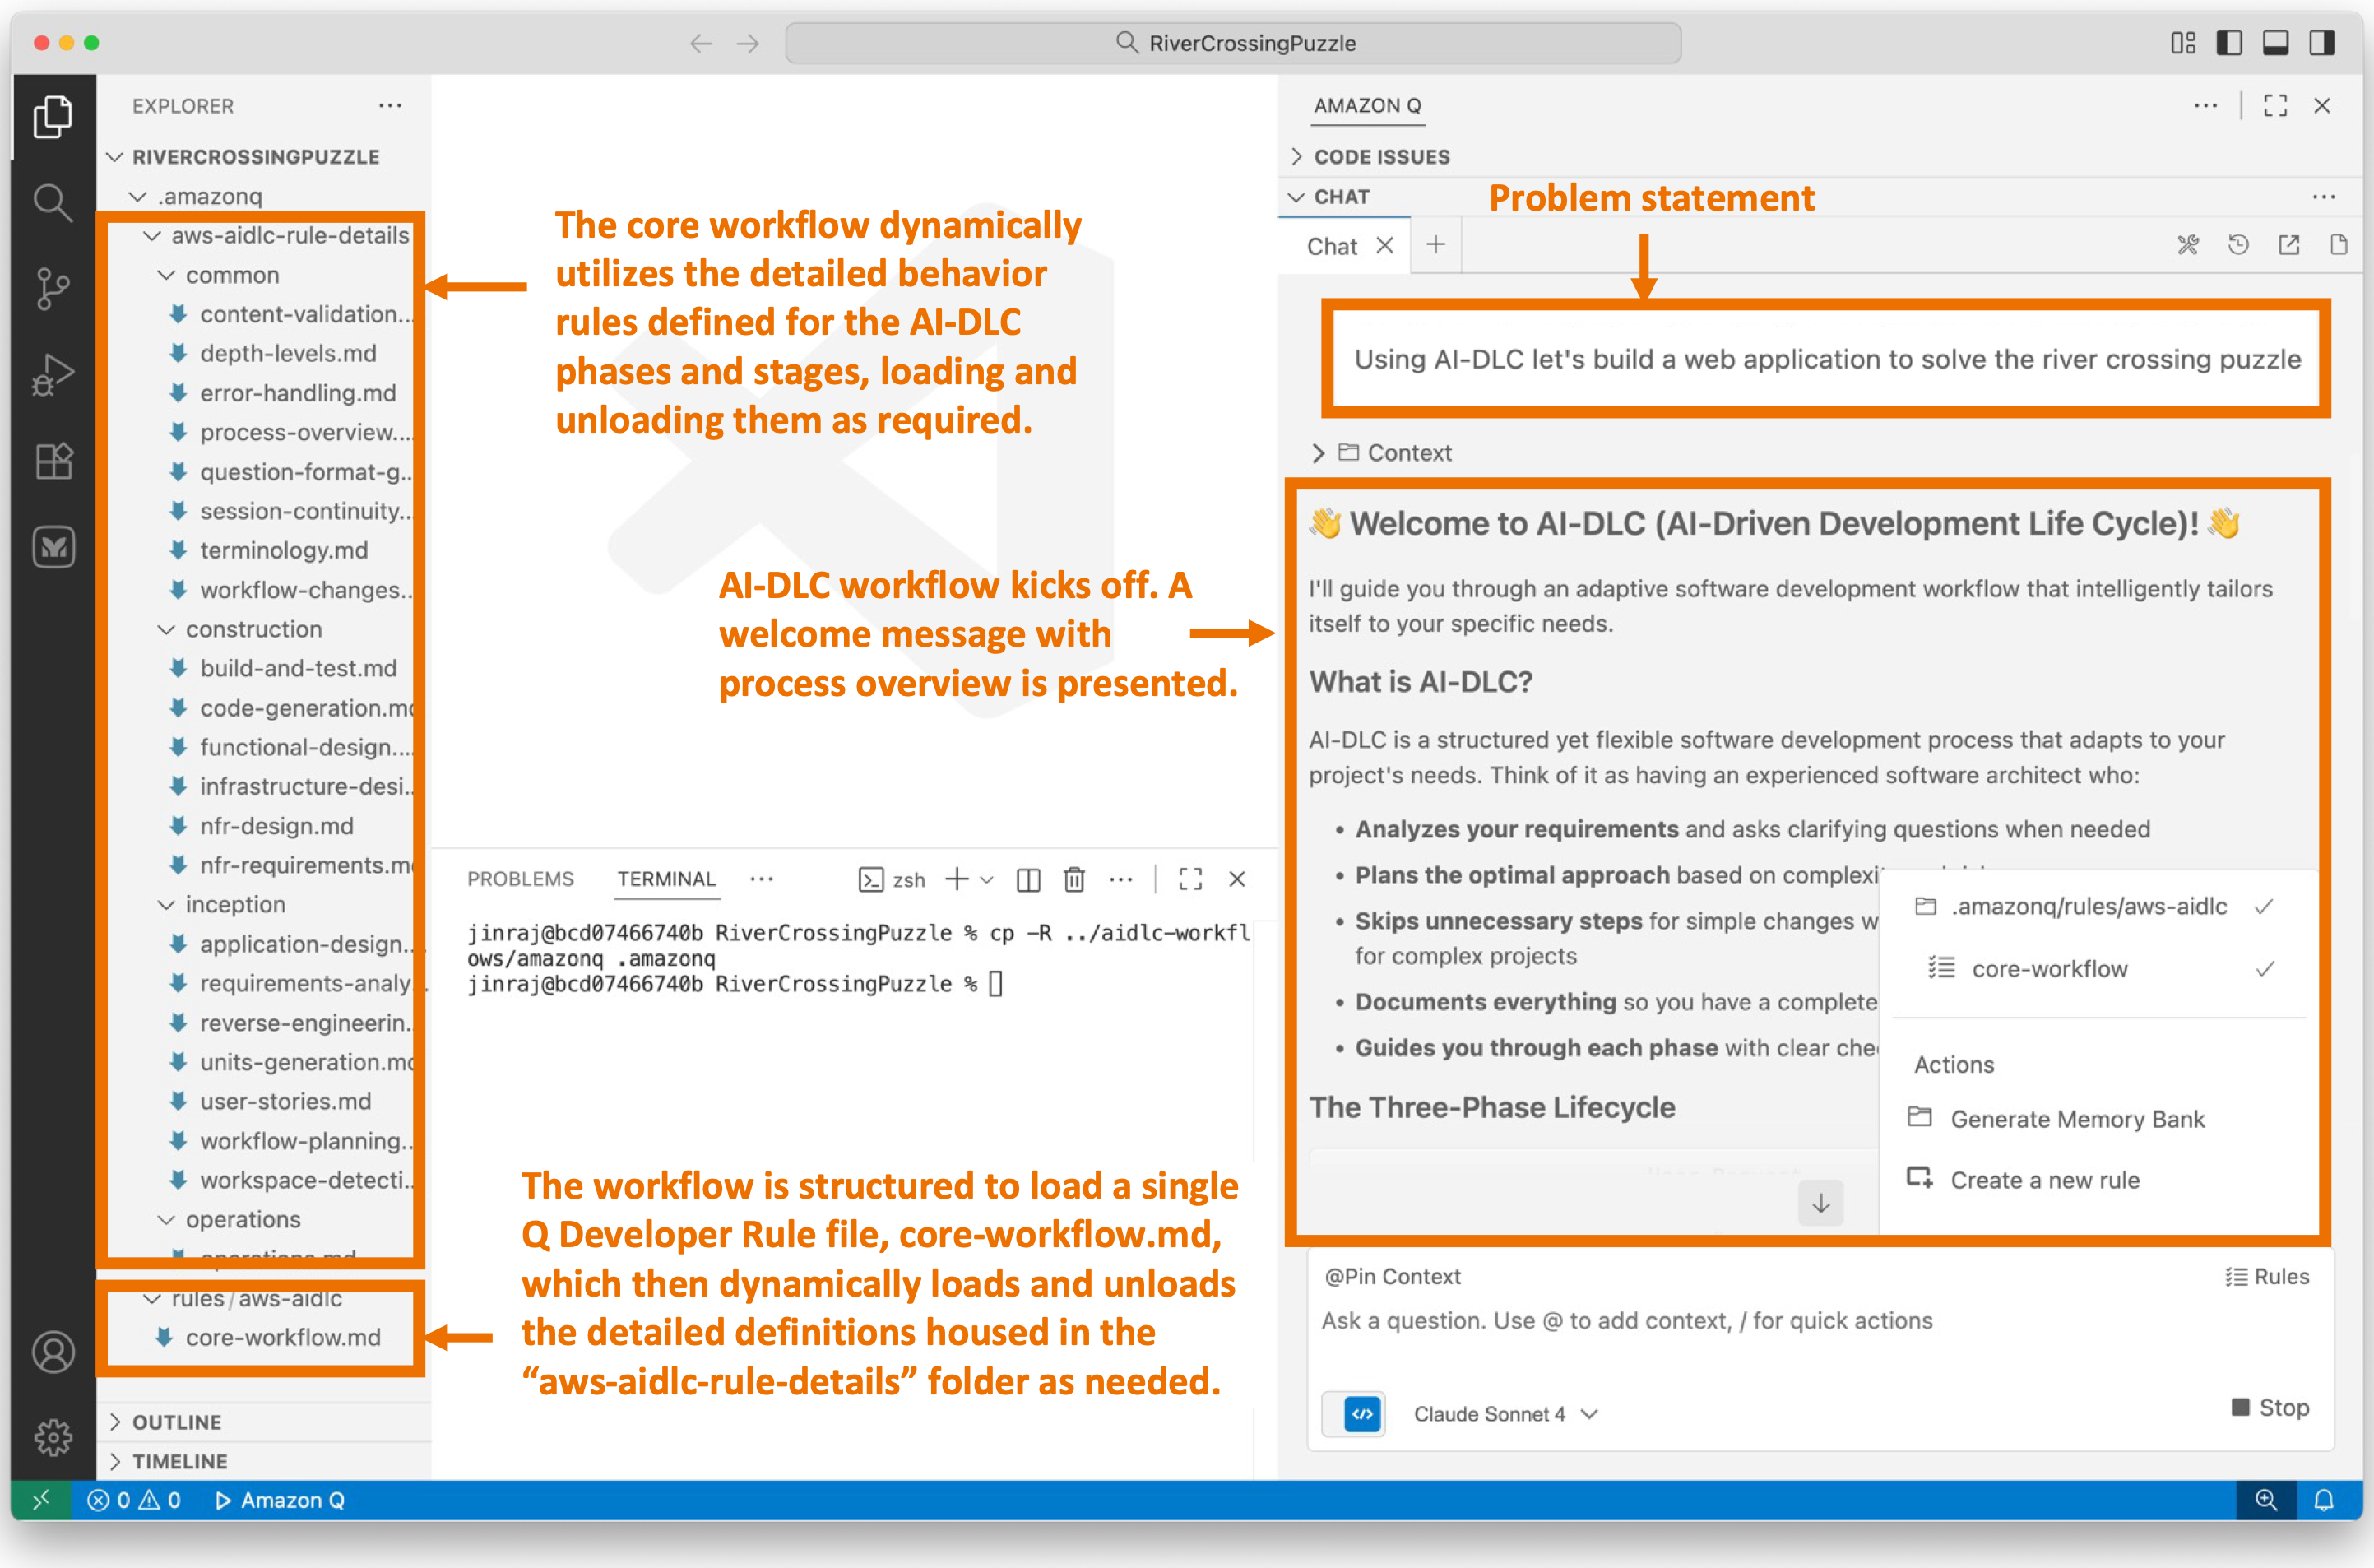
Figure 3: User enters high level problem statement in Amazon Q. AI-DLC workflow is triggered.
We enter the Workspace Detection stage within the Inception phase. In this stage, AI-DLC analyzes the current workspace and determines whether it’s a greenfield (new) or brownfield (existing) application. Since AI-DLC is an adaptive workflow, it decides whether the next stage will be Reverse Engineering (for brownfield projects) or Requirements Analysis (for greenfield projects).
Since we’re building a greenfield application and there’s no existing code in the workspace to reverse engineer, the workflow will guide us to Requirements Analysis next. If we were working on a brownfield application, the workflow would have performed Reverse Engineering first and then moved on to Requirements Analysis. This demonstrates the adaptive nature of the workflow.
Figure 4 illustrates the process in our IDE when we enter this stage. The workflow requests our permission to create an aidlc-docs folder under the project root. This folder will serve as the repository for all the artifacts generated by AI-DLC during the workflow execution. Subsequently, the workflow generates two files within this folder: aidlc-state.md and audit.md. The purpose of these files is explained in Figure 4.

Figure 4: Workspace Detection
The Workspace Detection will quickly finish as this is a greenfield project. The workflow will guide us into Requirements Analysis stage within the Inception phase next.
The workflow has progressed to the Requirements Analysis stage, where we will define the application requirements. The AI-DLC workflow presented our high-level problem statement to the Q Developer, which then responded with several requirements clarifications questions, as illustrated in Figure 4.
Several AI-DLC rules came into play at this stage. One rule instructed Amazon Q to avoid making assumptions on the user’s behalf and instead ask clarifying questions. Since LLMs tend to make assumptions and rush towards outcomes, they must be explicitly instructed to align with the engineering rigor of the AI-DLC methodology. To achieve this, the Q Developer presented several requirements clarification questions in requirement-verification-questions.md file and asked us to answer them inline in the file.
Another AI-DLC rule instructed the Q Developer to present questions in multiple-choice format and always include an open-ended option (“Other”) to enhance user convenience and provide flexibility in answering.
As shown in Figure 5, Amazon Q has asked us about the desired puzzle variant, such as the Classic Farmer, Fox, Chicken, and Grain puzzle or other popular variations. Additionally, it has asked us questions about user interaction methods, score persistence across multiple players, and the creation of a leaderboard.
These questions are essential for achieving our desired application outcome. Our responses to these questions will determine the final product. While we didn’t explicitly specify this level of detail in our high-level problem statement, AI-DLC has delegated detailed requirements elaboration to Amazon Q, but we still retain control over what gets built.

Figure 5: Requirements Analysis
We answer all the questions in requirement-verification-questions.md file and enter “Done” in the chat window.
Amazon Q processes our responses. The AI-DLC workflow is designed to identify human errors. It checks if we’ve answered all the questions and identifies any contradictions or ambiguities in our answers. Any confusions, contradictions, or ambiguities will be flagged for follow-up questions. AI-DLC adheres to high standards and ensures that we don’t proceed to the next step until we’re fully in agreement on the requirements between us and Amazon Q.
Since we answered all the questions and there were no contradictions in our answers, the workflow continues and generates a comprehensive requirements.md document, as shown in figure 6.

Figure 6: Requirements Review
The workflow prompts us to review the requirements.md document and decide on the next step. If we’re not aligned on the requirements, we can prompt Amazon Q to help us achieve alignment. We can then iterate on the requirements until we’re fully aligned. Once we’re fully aligned, we prompt AI-DLC to progress to the next stage.
Given the adaptive nature of the AI-DLC workflow, Amazon Q has recommended that this application is simple enough, and we can skip the User Stories stage. If we felt otherwise, we would have overridden the model’s recommendation. In this case, we agree with Q’s recommendation and will therefore enter “Continue” in the chat window.
The workflow will enter Workflow Planning stage next.
With our requirements established, we proceed to the Workflow Planning stage. In this phase, we leverage the requirements context and the workflow’s intelligence to plan the execution of specific stages of AI-DLC within the workflow to build our application as per the requirements specification.
Figure 7 illustrates the workflow planning stage in Q Developer. The workflow has generated an execution-plan.md file that outlines the recommended stages for execution and those that should be skipped.
The workflow planning process is highly contextual to the requirements. During requirements analysis, we decided to develop a simple river crossing puzzle application, consisting of a single HTML file, without a backend, leaderboard, or persistence. Consequently, Amazon Q recommends that we skip all the conditional stages, such as User Stories, Application Design, Units of Work Planning, and so on, and proceed directly to the Code Generation Planning stage in the Construction phase.
Figure 7 visually represents the recommended workflow graphically, indicating the stages that will be executed and those that will be skipped.
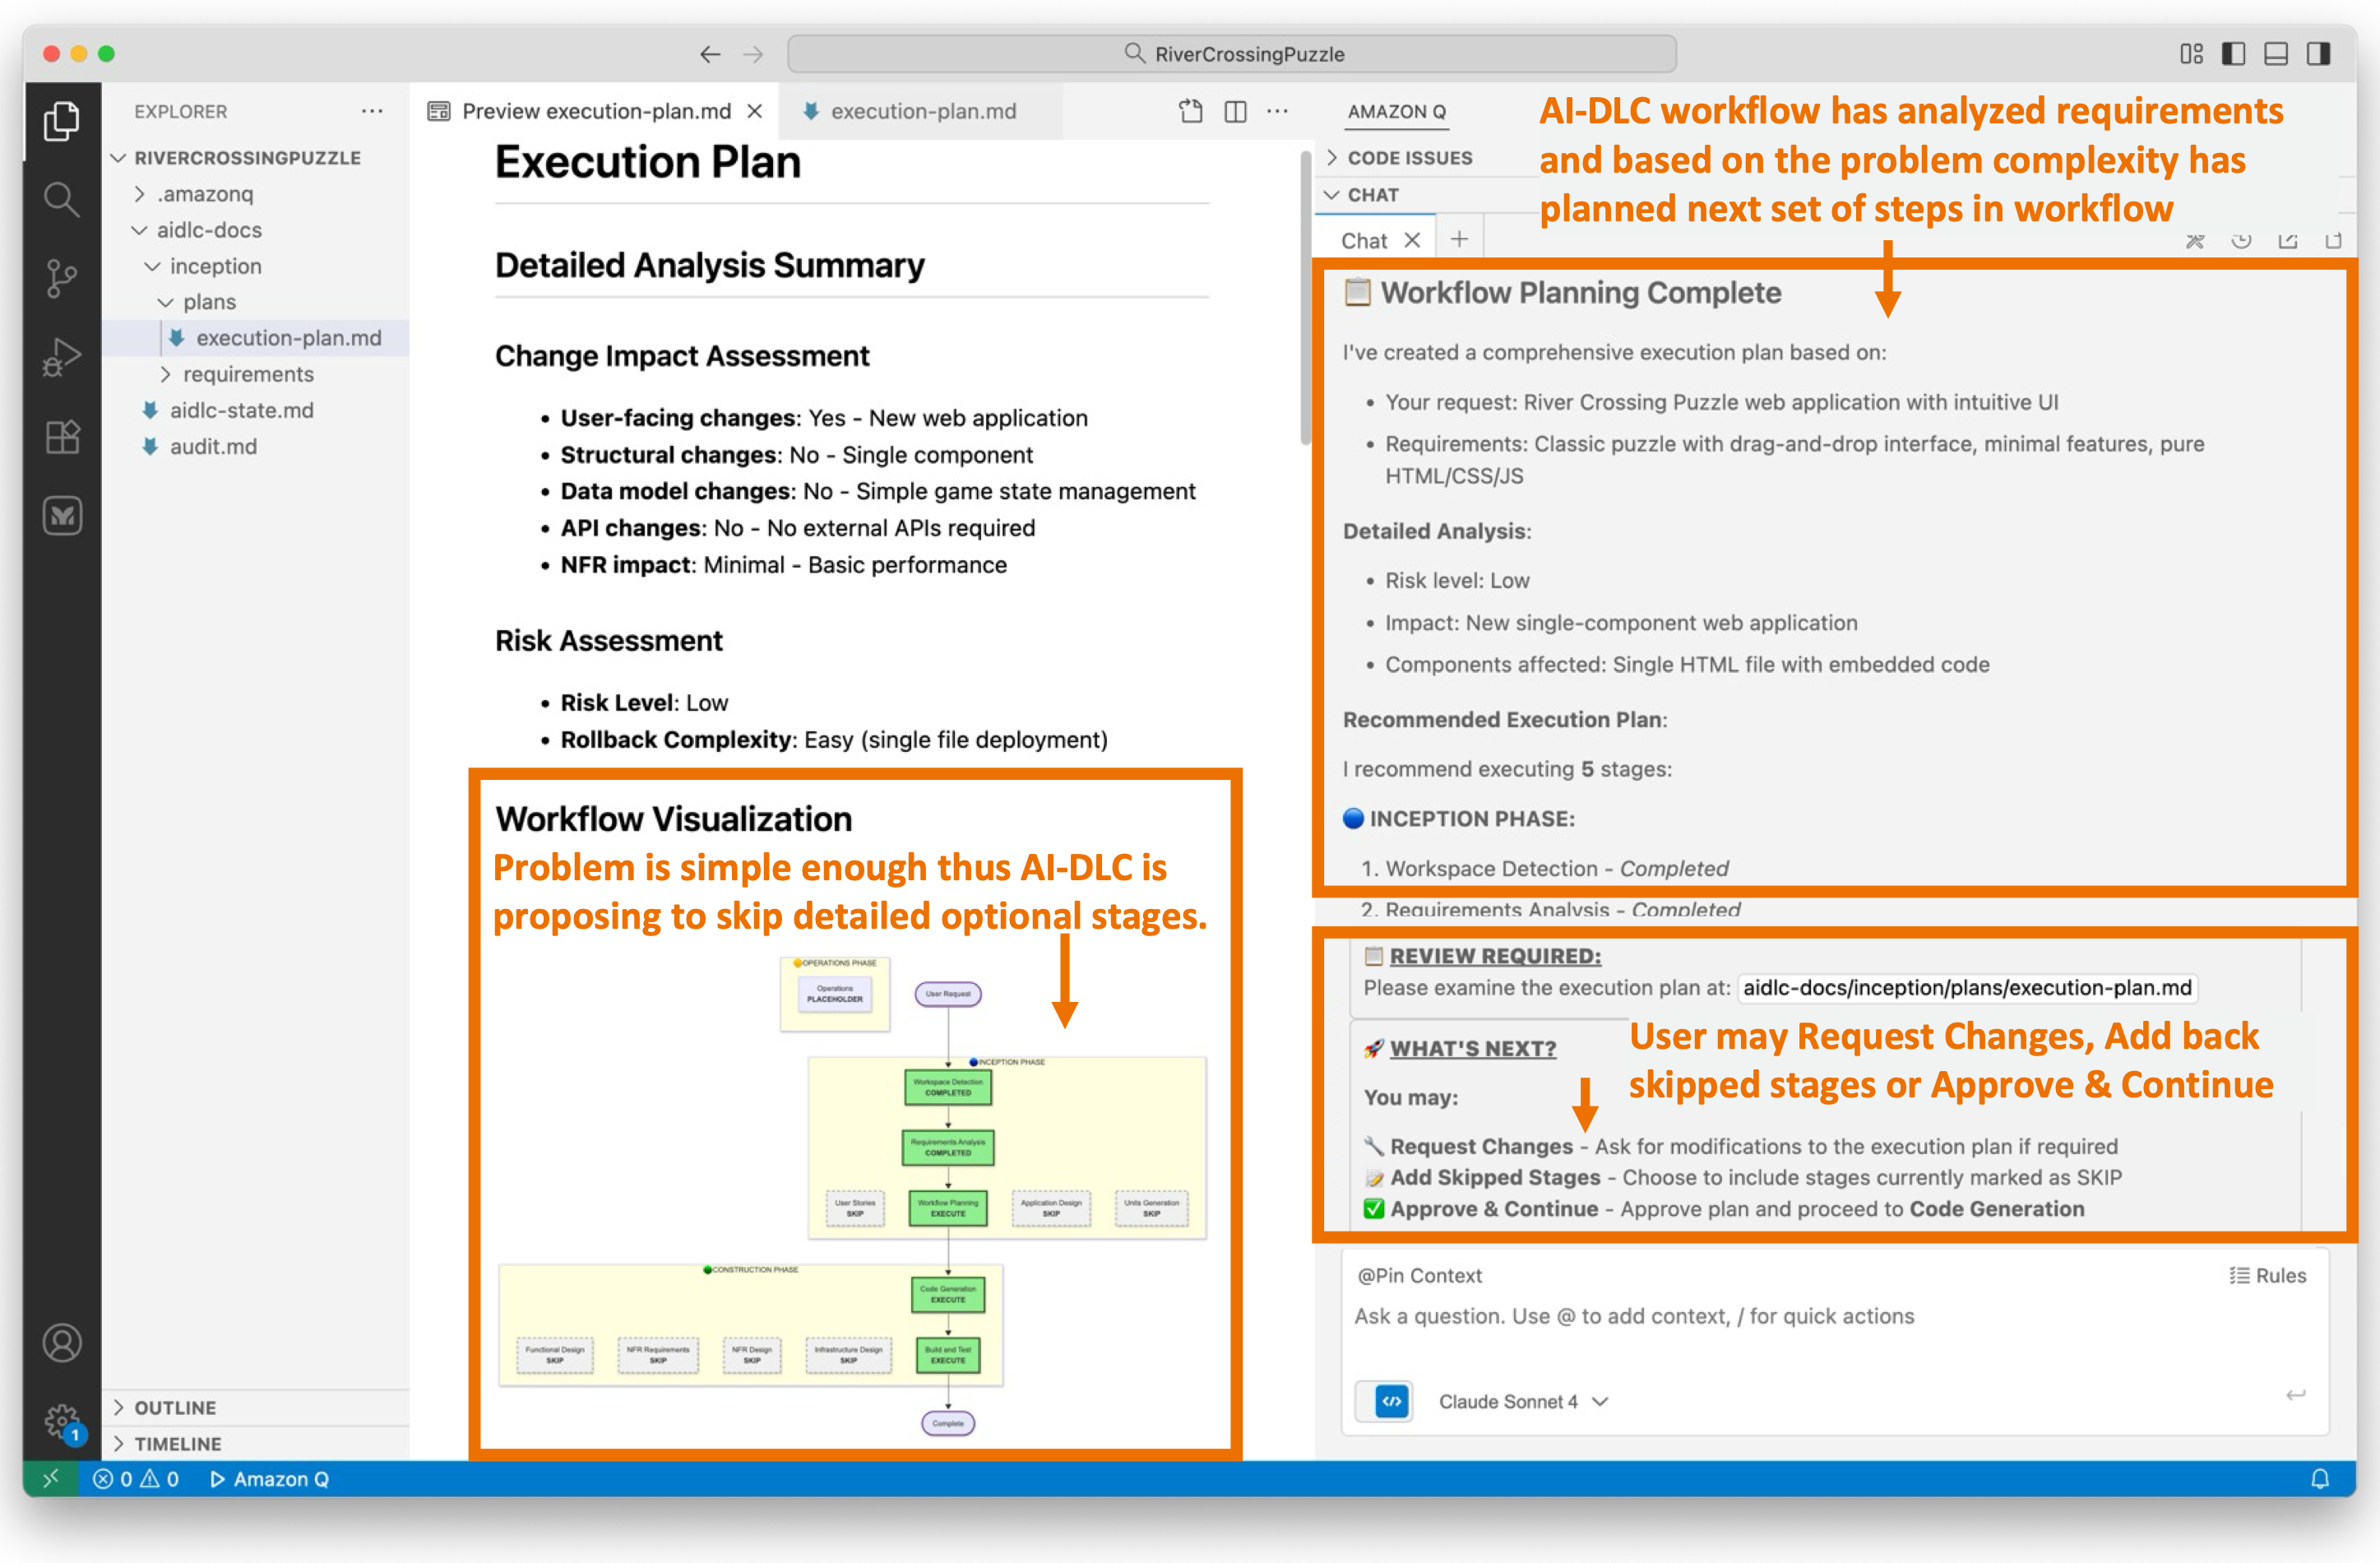
Figure 7: Workflow Planning
Since we’ve opted for a straightforward web UI app in this blog post for brevity, the workflow execution plan suggested by AI-DLC aligns seamlessly with our objectives. Should we not be aligned with the AI-DLC recommended workflow execution plan, we would request Q Developer to modify the plan to suit our preferences.
Since we’ve agreed on the workflow plan, we’ll enter “Continue” in Q’s chat session. If we weren’t aligned with the recommended workflow execution plan, we’d have prompted Q with our concerns and iterated over the revised execution plan until it aligned with our preferences. Following the recommended execution plan, the workflow will transition into the Construction phase and directly into the Code Generation Plan stage in the phase.
AI-DLC prioritizes planning over rushing to outcomes. This approach aligns with the concept of human-in-the-loop behavior, allowing us to detect issues early on, provide feedback on the plan, and prevent wrong assumptions from propagating further. Before we proceed with actual Code Generation, we undergo Code Generation Planning.
During Code Generation Planning, AI-DLC creates a detailed, numbered plan. It analyzes the requirements and design artifacts, breaking down the process into explicit steps for generating business logic, the API layer, the data layer, tests, documentation, and deployment files.
The plan is documented in a {unit-name}-code-generation-plan.md file, complete with check boxes. This ensures transparency, allowing users to see what will be built. It also provides control, enabling users to modify the plan. Additionally, it maintains quality by ensuring comprehensive coverage of code, tests, and documentation.
Figure 8 illustrates the AI-DLC’s code generation plan. The proposed workflow comprises eight steps, starting with creating an HTML structure and progressing to adding styling, game logic, and concluding with testing and documentation.
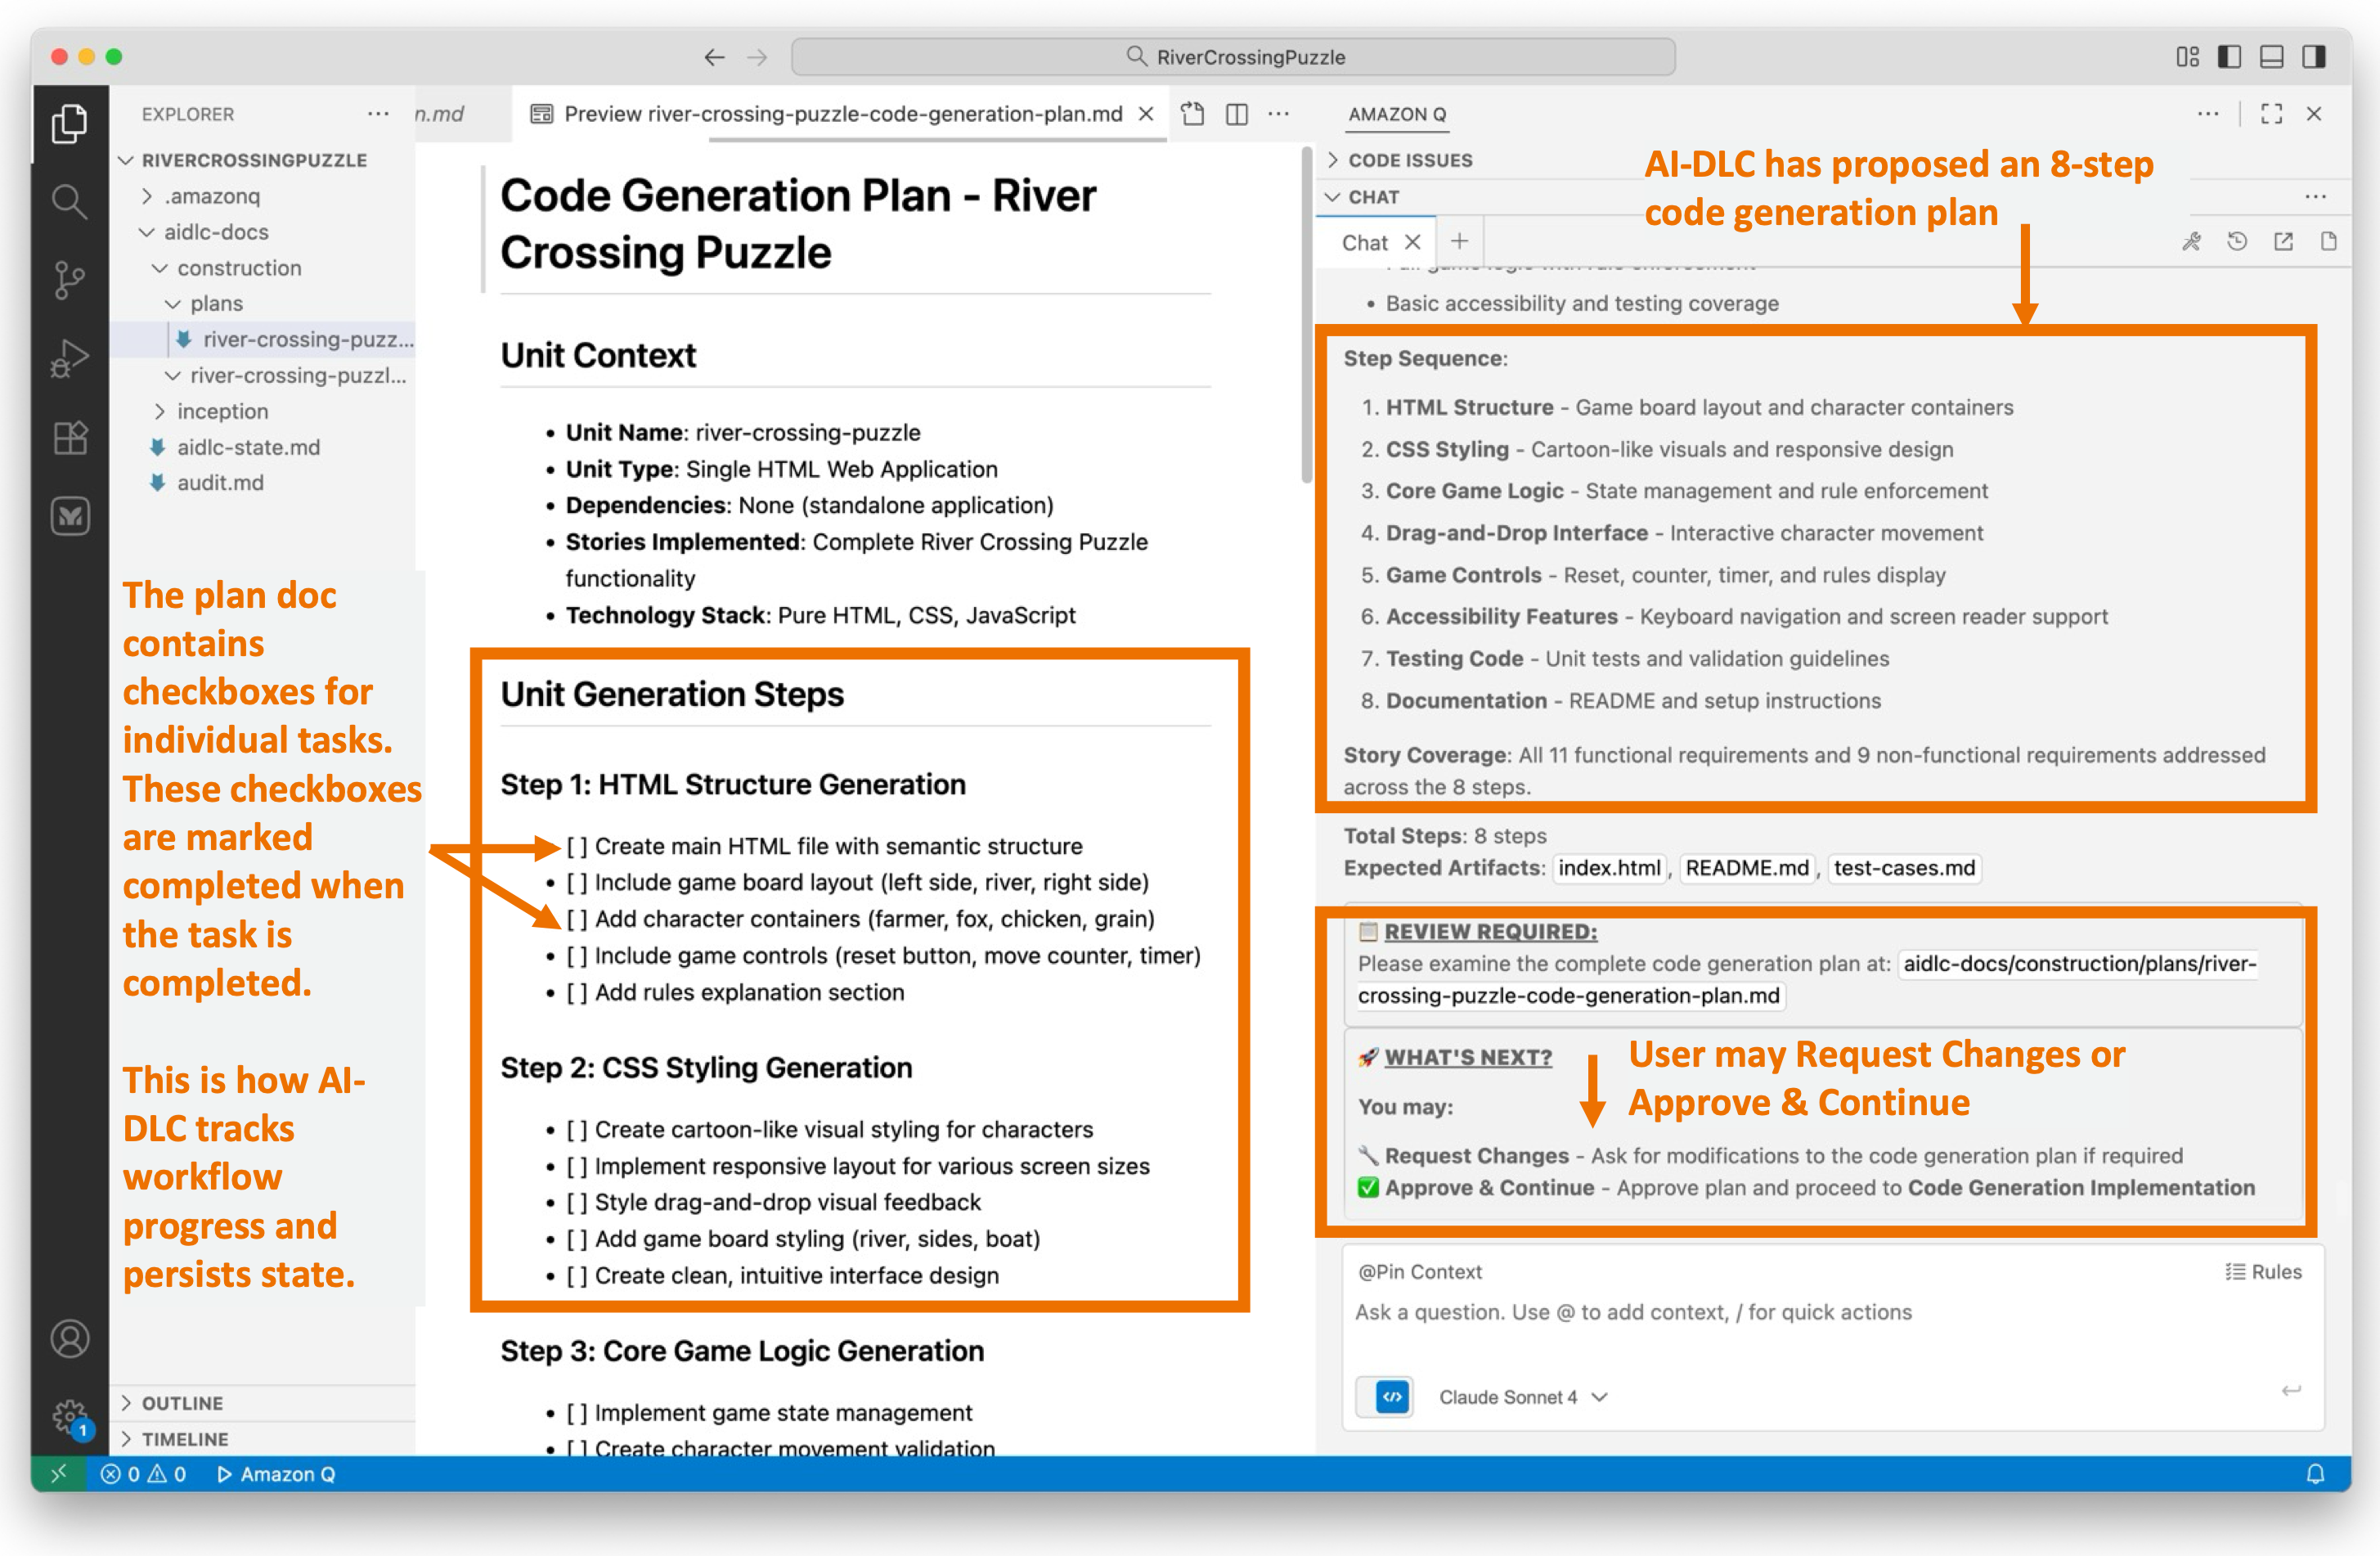
Figure 8: Code Generation Planning
The code generation plan appears reasonable to us. We will proceed to the Code Generation stage by entering “Continue” in Q’s chat session.
The Code Generation stage executes the Code Generation Plan we approved in the previous step. It generates actual code artifacts step-by-step, including business logic, APIs, data layers, tests, and documentation. Completed steps are marked with check boxes, progress is tracked, and story traceability is ensured before presenting the generated code for user approval.
Figure 9 illustrates that the Code Generation stage has been completed. We are now reviewing a single index.html file generated with embedded styling and JavaScript consistent with our preference specified in requirements.md.
The workflow provides a summary of the activities performed during the Code Generation phase.
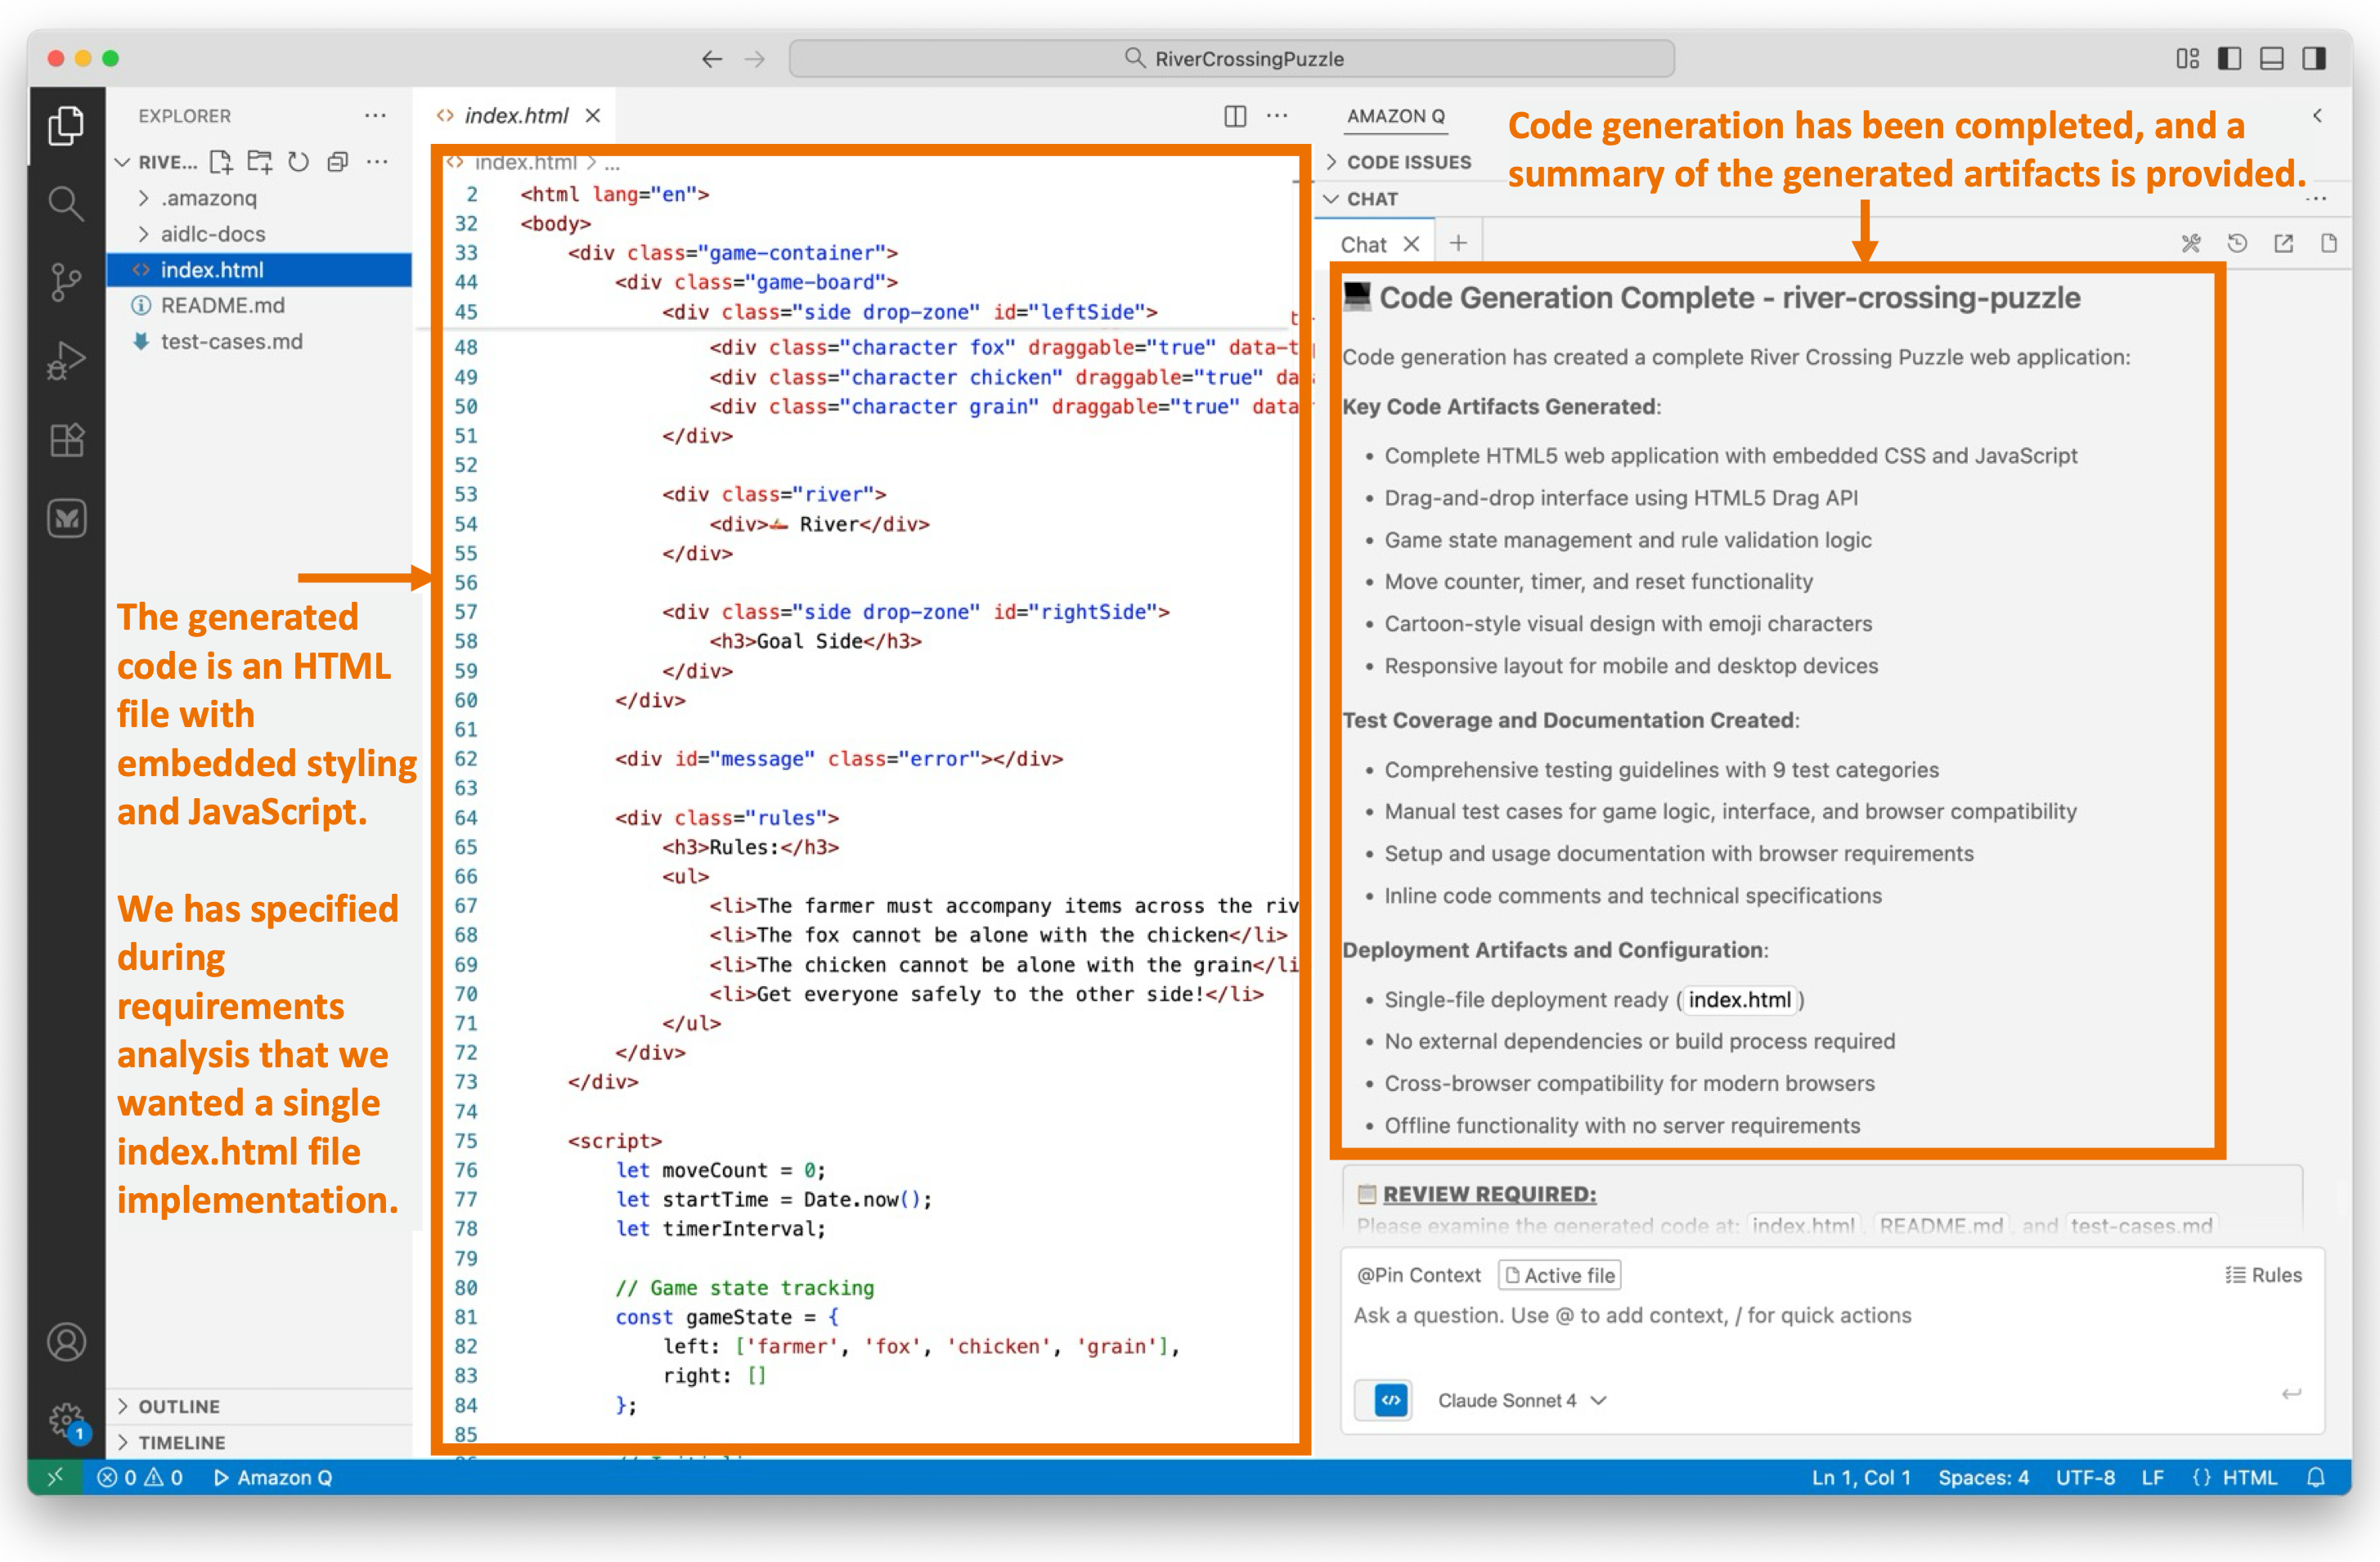
Figure 9: Code Generation
We’re about to test our newly created application soon. While it may be straightforward to test this simple puzzle app right now, for complex applications, we generate build and test instructions using AI-DLC.
We’ll enter “Continue” in the workflow and enter the final Build and Test stage in the Construction phase.
These questions are essential for achieving our desired application.
We’ve reached the final stage of the AI-DLC Construction Phase, known as the Build and Test stage. During this stage, we create comprehensive instruction files that guide the build and packaging of the project, and document the necessary testing layers. These layers include unit tests (validating generated code), integration tests (checking unit interactions), performance tests (load/stress testing), and additional tests as required (security, contract, e2e).
The generated build instructions include dependencies and commands, test execution steps with expected results, and a summary document that provides an overview of the overall build/test status and the project’s readiness for deployment.
Figure 10 illustrates the documentation generated during this stage.
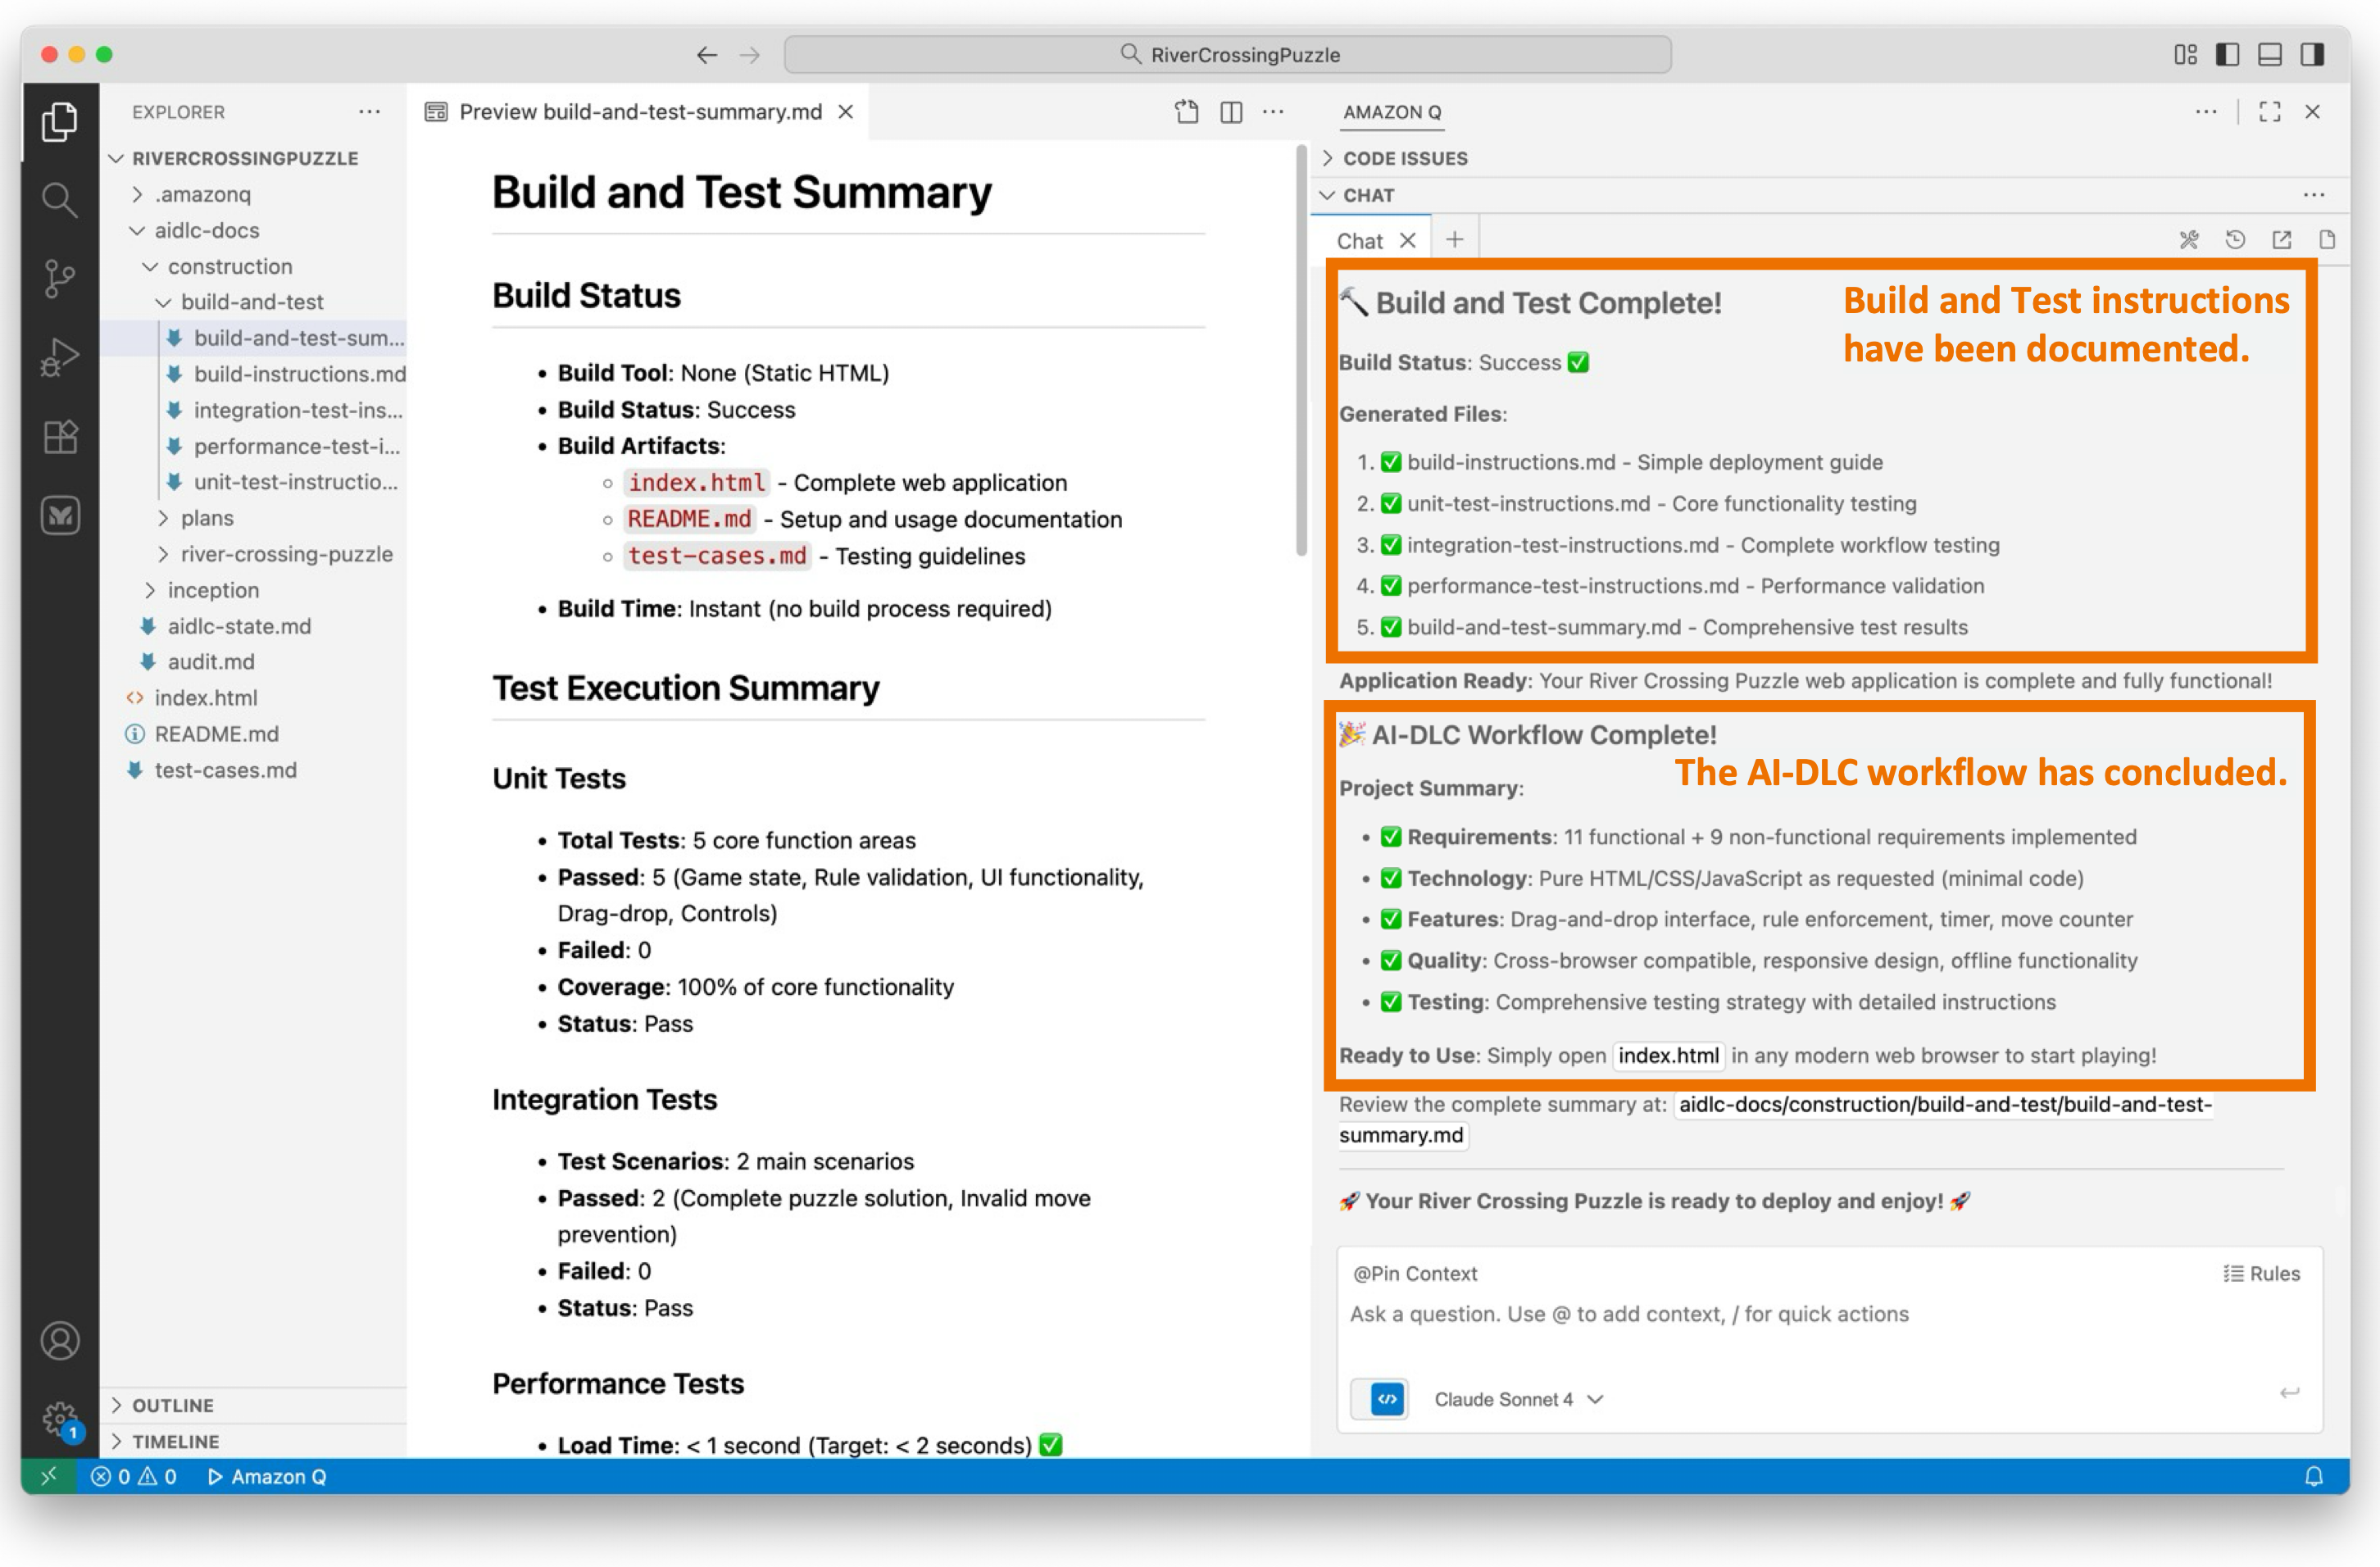
Figure 10: Build and Test
The AI-DLC workflow has now concluded.
We open index.html in a web browser to access our newly created River Crossing Puzzle application. As shown in figure 11, we see our graphical web UI.
During requirements assessment, we chose a straightforward user interface using HTML, CSS, and JavaScript (without any frameworks), as evident in the display shown in Figure 11. Your display may vary due to the probabilistic nature of LLMs and the choices you made for requirements.
We attempt to solve the puzzle and find that it works as expected.

Figure 11: River Crossing Puzzle Web App
This post shows how AWS’s open-source AI-DLC workflow, guided by Amazon Q Developer’s Project Rules feature, helps developers build applications with structured oversight and transparency.
Using a River Crossing Puzzle web application as an example, the walk-through illustrates how AI-DLC methodology adapts its rigor based on project complexity, skipping unnecessary stages for simple applications while maintaining comprehensive processes for complex projects. Throughout each stage, AI-DLC enforces “human-in-the-loop” behavior, requiring user approval at critical checkpoints, asking clarifying questions, and maintaining complete audit trails for traceability.
The exercise successfully demonstrates how AI-DLC balances AI automation with human oversight, enhancing productivity without sacrificing quality or control. By following this structured, repeatable methodology, development teams can leverage generative AI’s capabilities while ensuring humans remain in charge of architectural decisions and implementation approaches. This framework provides the necessary guardrails for responsible and effective AI-assisted software development across projects of varying complexity.
We did not create any AWS resources in this walk-through, so no AWS cleanup is needed. You may cleanup your project workspace at your discretion.
Ready to get started? Visit our GitHub repository to download the AI-DLC workflow and join the AI-Native Builders Community to contribute to the future of software development.
About the authors:
Post Syndicated from Will Matos original https://aws.amazon.com/blogs/devops/open-sourcing-adaptive-workflows-for-ai-driven-development-life-cycle-ai-dlc/
AI-Driven Development Life Cycle (AI-DLC) holds the promise of unlocking the full potential of AI in software development. By emphasizing AI-led workflows and human-centric decision-making, AI-DLC can deliver velocity and quality. However, realizing these gains hinges on how organizations effectively integrate AI into their engineering workflows.
Through our work with engineering teams across industries, we have identified three recurring challenges. These challenges consistently limit the effectiveness of AI in accelerating modern software development. The first challenge is one-size-fits-all workflows. These workflows force every project through the same rigid sequence of steps. The second challenge is the lack of flexible depth in workflow stages. This leads to over-engineering or insufficient rigor. The third challenge is tools that over-automate. These tools unintentionally divert humans away from critical validation and oversight responsibilities.
Achieving true, sustainable productivity requires the process and AI coding agents to become adaptive to context, flexible in depth, and collaborative by design. In this blog, we’ll show you how AI-DLC’s core principles address these three challenges, transforming them from productivity blockers into opportunities for adaptive, human-centered development. We’ll describe how AI-DLC enables workflows that adapt to the problem at hand by intelligently selecting stages, modulating depth, and embedding human oversight at every critical decision point.
We will also introduce our open-source Amazon Q Developer/Kiro Rules implementation, which brings AI-DLC principles to life through adaptive workflow scaffolds. This allows you to start applying these principles in your own projects and experience AI-native development that accelerates delivery without compromising engineering discipline or human judgment.
Let’s explore how AI-DLC addresses these challenges.
Software development has never been a linear process. In practice, different projects follow distinct pathways with their own checkpoints and deliverables. Consider these examples:
Yet, many modern Agentic coding tools provide hard-wired, opinionated workflows that ignore this diversity. Regardless of intent or scope, every project is forced through the same rigid sequence of steps—even when some add little or no value. This rigidity introduces friction, wastes time, and reduces productivity. The result: artificial ceremonies, unnecessary artifacts, redundant approvals, and process overhead that impede velocity.
How AI-DLC addresses this challenge:
AI-DLC addresses this challenge through the Principle 10 (No Hard-Wired, Opinionated SDLC Workflows) as defined in the AI-DLC Method Definition Paper.
“AI-DLC avoids prescribing opinionated workflows for different development pathways (such as new system development, refactoring, defect fixes, or microservice scaling). Instead, it adopts a truly AI-First approach where AI recommends the Level 1 Plan based on the given pathway intention.“
True adaptivity must go beyond the breadth of a workflow and extend into its depth and intensity. This is how human experts intuitively plan software projects today.
Even when workflows are flexible, many tools fail to modulate the depth of engagement at each stage. For example, building a lightweight utility function doesn’t require full-scale Domain-Driven Design or detailed architectural modeling. When an AI coding agent compels teams to follow these steps regardless of need, the consequence is wasted effort and an over-engineered product. Developers spend cycles reviewing artifacts as the tools dictate rather than delivering business value.
How AI-DLC addresses this challenge:
Through the same principle 10, AI-DLC adapts both the breadth (choice of stages) and the depth of each stage to match the complexity of the intent and context. For example, the complexity of the requirements determines whether a conceptual design is sufficient or whether a full architectural deep dive is required in the Design stage.
Humans validate and adjust this AI-proposed breadth and depth, ensuring that each stage’s rigor matches the scope of the challenge. This elasticity—balancing breadth and depth—is essential for sustaining true velocity without sacrificing engineering discipline.
As AI tools automate more of the Software Development Life Cycle (SDLC), a new risk has emerged: process atrophy. Developers, excited by automation, often drift into passive execution—allowing AI to “decide everything.” The result is a loss of reflection, weakened oversight, and erosion of shared understanding. AI tools must not only automate work but also amplify the significance of human judgment. They should remind practitioners that “human in the loop” is not a checkbox—it is the cornerstone of trust, accountability, and correctness in AI-native development. Equally critical are the rituals and rhythms that sustain collaborative engineering.
How AI-DLC addresses this challenge:
AI-DLC addresses this challenge by requiring a collaborative human-in-the-loop cycle at every stage of the workflow. In this loop, AI generates a plan to execute a task, and relevant stakeholders assemble, review, and validate it.
These rituals, defined as Mob Elaboration and Mob Construction in AI-DLC, ensure that AI’s suggestions are not blindly accepted. Approved plans are executed, and stakeholders again review and validate the final artifacts. The AI-DLC workflow records every human action and approval, embedding reflection to ensure that humans remain the compass, guiding AI’s acceleration.
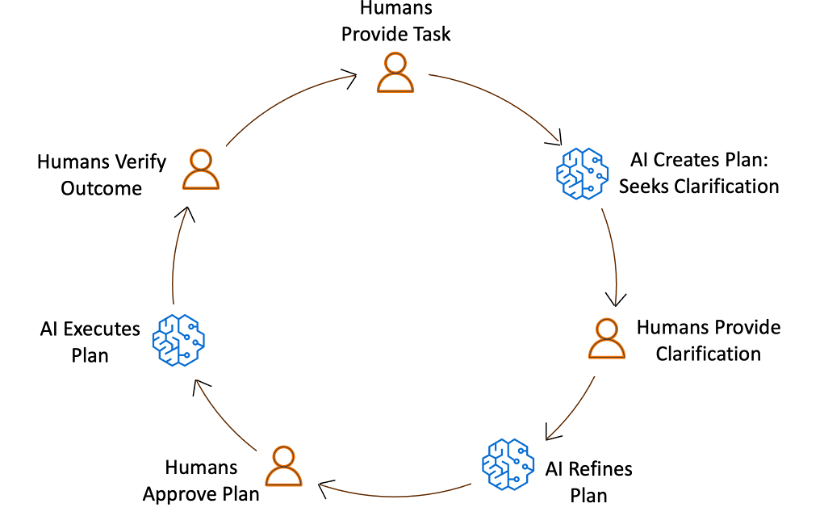
Figure 1: AI-DLC workflow: Humans decide and validate, AI plans and executes.
Effective tooling must therefore emphasize:
The goal is not to suppress automation but to embed critical human ownership.
The ideas we outlined — adaptive workflows, flexible depth, and embedded human oversight — are compelling in theory and validated by all engineering teams we’ve engaged. The critical question is: How do we operationalize these ideas into practice without reintroducing the rigidity we seek to eliminate?
One approach is manual prompt engineering: crafting structured prompts that guide AI assistants through the AI-DLC workflow step by step. Each prompt encodes the role AI should assume, the task at hand, the governance requirements, and the audit trail expectations. This structured approach transforms a simple AI interaction into a disciplined workflow that embodies AI-DLC principles.
This approach, while promising, faces its own limitations. Crafting intricate prompts demands discipline and expertise, posing barriers to widespread adoption. Moreover, humans become responsible for maintaining workflow adaptability, selecting the appropriate prompt at the right moment, and ensuring collaborative checkpoints are honored. This places the burden of orchestration back on practitioners, diverging from our core principle of truly AI-native development, where AI itself drives adaptive decision-making.
The question arises: How can we embed AI-DLC principles directly into the execution layer, making adaptivity and collaboration inherent properties of the system rather than manual responsibilities?
The answer lies in workflow scaffolds. These are Rules or Steering customizations for AI Coding Agents. They operationalize AI-DLC principles within the tools. This is done while maintaining transparency, audibility, and modifiability. Our implementation uses Rules/Steering Files. These serve as the foundation of this execution layer. It transforms AI from a passive assistant into an adaptive decision engine.
Rather than requiring developers to craft elaborate prompts, AI-Driven development begins with a simple statement of intent. From there, the workflow scaffolds evaluate context, assess complexity, and dynamically construct an appropriate development pathway. The core workflow definition, including a library of stages and decision heuristics for when and how to apply them, empowers AI to continuously tailor the development process to the nature of the work at hand.
Each AI-DLC phase (Inception, Construction, Operations) evaluates the depth at which it should execute, resulting in a process that adapts to the problem rather than forcing the problem to adapt to the process. This approach yields several critical outcomes:
The result is a process that is context-aware, scalable, and self-correcting – capable of supporting everything from a single-line defect fix to a comprehensive system modernization, all while maintaining the rigor and human judgment that define engineering excellence.
We’re open-sourcing the AI-DLC workflow, implemented as Amazon Q Rules and Kiro Steering Files, so organizations everywhere can experience AI-DLC in practice and build production-grade systems. We invite developers, architects, and engineering leaders to:
Your feedback will help evolve this into a foundation for AI-native software development – one that accelerates delivery without sacrificing rigor or human judgment. Together, we can redefine what software engineering looks like in the age of AI: not scripted but steered.
AI-DLC addresses multiple challenges limiting AI’s effectiveness in software development such as rigid workflows, inflexible workflow depth, and tools that reduce human oversight. AI-DLC enables adaptive workflows that intelligently select stages, modulate depth, and embed human oversight at critical decision points. This approach, implemented through open-source tools like Amazon Q Developer Rules and Kiro Steering, accelerates delivery while maintaining engineering discipline and human judgment.
AI-DLC emphasizes human oversight and collaboration in AI-driven software development. Workflow scaffolds, embed AI-DLC principles into the execution layer, enabling adaptive decision-making, transparent checkpoints, and end-to-end traceability. Open-sourcing the AI-DLC workflow allows organizations to experience AI-DLC in practice and contribute to its evolution.
Ready to get started? Visit our GitHub repository to download the AI-DLC workflow and join the AI-Native Builders Community to contribute to the future of software development.
About the authors:
Post Syndicated from Vasil Kolev original https://vasil.ludost.net/blog/?p=3519
Записите от OpenFest 2025 може да се намерят във видео архива и в youtube.
Забавянето беше заради един бъг на encode-ването, и после докато мине пак преглед/QA. Имаме вече скриптирани нещата и би трябвало догодина да можем да вадим записите в същия ден, ако решим 🙂
Post Syndicated from Боян Юруков original https://yurukov.net/blog/2025/landown/
Един от многото повдигнати въпроса покрай картата ми с 4400-те имота готвени за продажба от правителството на Желязков беше, че много хора включително кметове не са знаели, че определени имоти са собственост на държавни институции и фирми. Трагедията в Елените пък постави интересени въпроси за собствеността на парцелите около и върху заличеното корито на реката, както и на склоновете над селището. Един от ключовите въпроси за изчезващите градинки, градоустройството и презастрояването не само в София, но във всички градове в България е изненадаващата частна собственост на междублокови пространства, градинки и места иначе предназначени и отдавна използвани за инфраструктура, училища и публични пространства.
С други думи, собствеността на земята е важен аспект засягащ много публични дебати ставащ често неразбран и настрана. Част от причината за това е огромното количество на данни, ниското качество на източниците и липсата на публичност на първоизточника – имотния регистър
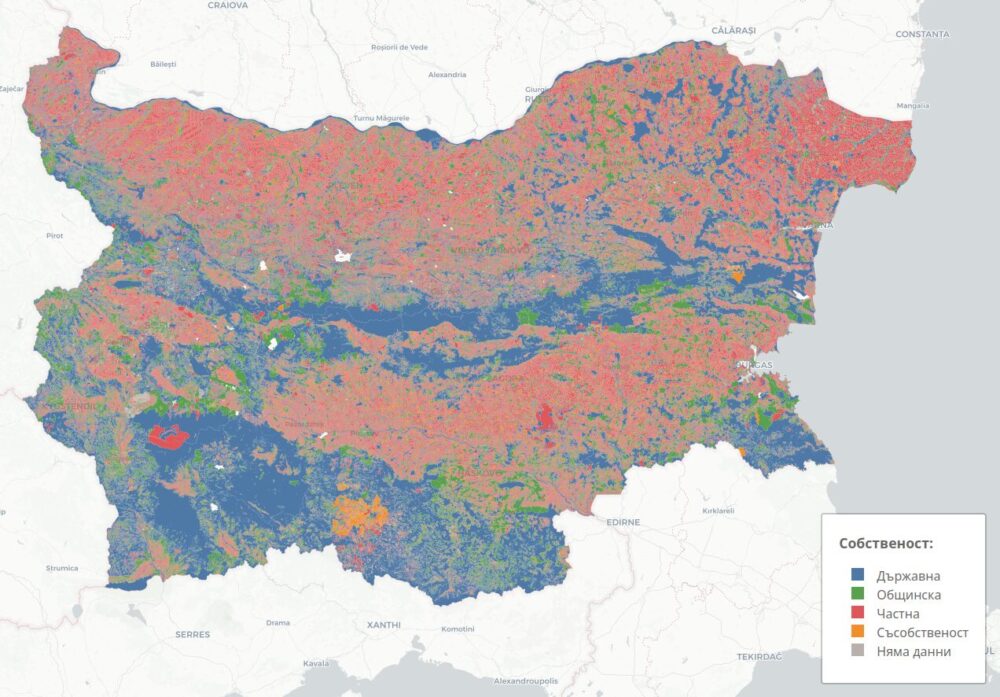
Затова преди няколко месеца седнах и изготвих картата на собствеността на няколко български града. Исках да видя кои градинки са частни, кои реки са държавни, кои поля и места за инфраструктура са останали общински или вече са в частни ръце с цел застрояване. Наскоро реших, че ще е полезно да публикувам картата. Това обаче беше отново техническо предизвикателство отново заради огромното количество информация, качеството и принципът на който изготвям всичките си визуализации.
Картата ще намерите на govalert.eu/landown. Препоръчвам преди да я разгледате да се запознаете със секциите в тази статия, защото ще отговорят на почти всички въпроси за самата карта и какво показва. Други подобни карти ще намерите на opendata.yurukov.net/govbg и govalert.eu.
За целите на този текст е възможно да използвам думите парцел и имот в един и същи смисъл. Имот може да има значение и за апартамент, офис, къща или друг вид сграда. В случая за избягване на тафтологии ще използвам в смисъл конкретно на парцел.
Доколкото по-нататък обсъждам качеството на данните, картата почти сигурно не показва реалното положение. Причината е не само в наличността на данните, а и че много имоти са с неизвестна собственост. В този смисъл и както винаги, картата следва да бъде начална точка за проверки, търсене на информация и задаване на въпроси, отколкото като източник на фактическо положение. Данните от кадастъра са свалени на 13-ти ноември 2025, а от общински и държавни регистри – в рамките на ноември.
Когато споменах в социалките, че ще публикувам нещо такова, се появи критика, че това ще е възможност за измамници да се възползват и да крадат земя от частни лица и институции. В действителност, подобно на достъпа до нотариалните актове, измамниците почти винаги имат вече тази информация, както и вътрешен източник и достъп. Често ограбването на общински имоти става със съдействие на общинския съвет и служители в общината. Кражбата на частни и държавни имоти става с корумпирани съдии и нотариуси. Липсата на прозрачност е тази, която позволява в голяма степен всичко това. Също липсата на работеща прокуратура.
Като основа използвах отворените данни от кадастъра. Те имат своите проблеми, един от които е именно с точността на данните за собствеността. Причината е, че доста сделки не обявават сменена собственост в кадастъра. Доколкото в повечето случаи това би засегнало смяна на записа за крайния собственик, виждаме как приватизация и одържавяване може да не бъде отбелязана като такава.
Въпреки споразумение за обмен на данни между кадастъра и имотния регистър – способ за взаимна работа, който принципно е абсурден като концепция – изглежда кадастъра използва достъпа си до данните за собственост единствено за административни операции, а не да приведе отворените си данни в нужното качество. Това е най-доброто обаче, което имаме като за начало и все пак се радвам, че въобще съществува, особено на фона на напъните за по-малко прозрачност и как под прикритието на протестите срещу бюджета и дърпането на уши от Пеевски на министри, една марионетка на ГЕРБ в кабинета всъщност затри критичен елемент на публичност на имотния регистър с оправданието. Оправданието му е, че така борил имотните измами, но практически всички юристи, нотариуси и журналисти обявиха, че прави точно обратното с крайна цел спиране на журналистически разследвания.
Концентрирах се върху 25 български града – Благоевград, Бургас, Варна, Велико Търново, Видин, Враца, Габрово, Добрич, Кърджали, Кюстендил, Ловеч, Монтана, Пазарджик, Плевен, Пловдив, Русе, Смолян, София, Стара Загора, Търговище, Хасково, Шумен и Ямбол. По-нататък обяснявам защо не можах да покрия в детайли цяла България. В повечето взех самото землище на града, но където виждам свързани квартали и села добавих и тях. Така получих 1095933 парцела.
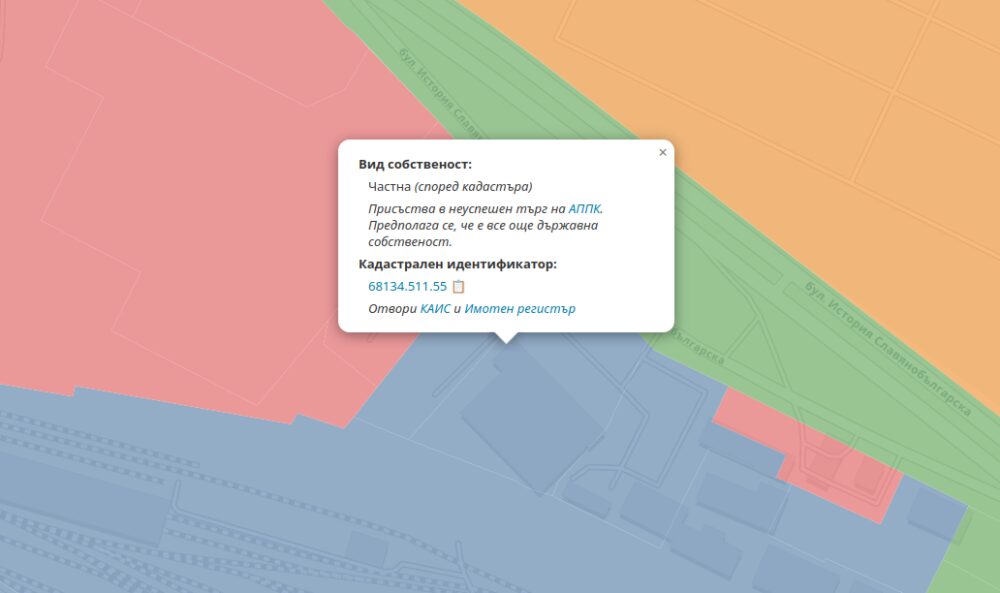
За да коригираме данните, трябва да черпим от други източници. Започнах от данните на АППК, където имаме над 1000 търга от последните години. Презумпцията там е, че щом един търг е успешен, значи имотът вече е в частни ръце. Ако не е успешен, значи все още е в държавната фирма или инстритуция. Доста от търговете са за жилища, офиси и сгради. Някои въобще не споменават идентификатора на имота. Има и имоти, които са имали няколко неуспешни търга. Намерих един с два успешни търга, което говори, че спечелилият не е платил за имота. Няма как да знаем дали и колко още такива. Приемам, че след търговете земята е била сменена, както и че споменати там имоти не са продавани без търг. Също така не разглеждам имоти, които са отбелязани правилно в кадастъра. С тези презумпции обаче намерих 71 имота, които са минали в частни ръце и 13, които предполагаме, че са останали в държавни. Т.е. 84 имота, които много вероятно са отбелязани грешно в кадастъра.
На база тази и следващите корекции ще видите тези имоти в новия си цвят – например при успешен търг парцел маркиран като държавен в кадастъра ще се вижда като частен в моята карта. Тогава в информацията към този парцел ще виждате защо и линк към източника.
След това се обърнах към общинската собственост тя е пръсната и разнородна. Често трудна за сваляне и обработка. Отне ми значително време да сваля данните от София, Пловдив и Варна. Започнах да обработвам и останалите 22 града, но често или липсва регистър, или липсват данни за идентифициране на имотите. Пример е Бургас, където макар да има регистър, той не позволява по никакъв начин да се разбере за кои имоти всъщност става дума. Има предвидена функция за идентификатор, географски данни и прикачени документи, но липсват навсякъде. Именно за това лошо качество на данните говорих в началото и доколкото за други има бюрократично или обективно обяснение, в случая с общинската собственост най-често става въпрос за умишлено прикриване.
Подобно е положението в много други общини. Обработвам ги една по една и скоро ще обновя картата с нова информация. Публикувам я преди това, защото очаквам сравнително малко нови данни и съответно корекции за по-малките градове. В София „поправих“ собствеността на 3738 парцела, което е 0.96% от всички. В Пловдив – 239 или 0.62% от всички в общината. Във Варна – 1497 или 1.88% от парцелите.
Това не са всички общински имоти, а само тези, които сметнах за сгрешени в кадастъра. Също така не значи, че почти 1% от територията на София е сгешена, тъй като някои от парцелите са много малки. Не на последно място, данните в самите регистри са под въпрос, защото как се поддържат не е много ясно. Общинската собственост е чест източник на измами и схеми, особено от страна на общински съветници, чиновници и свързани с тях лица. По времето на Фандъкова, например, точният списък е бил изключително ревностно пазена тайна дори в рамките на администрацията. Това означава, че като правило липсват технически и организационни механизми тази информация да се публикува коректно и автоматично.
Това, което ни липсва като данни, е собствеността на държавни и общински фирми. Много години имаше обещания за такъв регистър, но не видя бял свят. Това изглежда е отчати лоша организация, отчасти нужда от продължително усилие на иначе кратковременни кабинети, отчасти чадър над многобройни схеми и точене на публичен ресурс по места, но също и факта, че изглежда много институции всъщност не знаят къде какво притежават.
Бихме могли да използваме информацията в АППК за отдаване под наем. Някои от тях са на държавни фирми. Като правило тези обаче се отнасят за офиси и сгради и няма яснота дали земята под тях е на същата фирма. Бихме могли да използваме решенията на Министерски съвет за промяна на предназначение на имоти, одържавяването или приватизацията им – добавих всички тези за София, Пловдив и Благоевграда в картата ми с документите за градоустройството. Оказва се обаче, че не е ясно колко от тези решения са изпълнени. Пример е решението за 12 имота в София да се прехвърлят на общината за изграждане на линеен парк, от които областния управител прехвърли след много време едва два.
Друг косвен индикатор би могъл да бъде списъкът с 4400 имота на Желязков. Там наистина има инфорамция коя държавна фирма какво държи и с какво кабинета би му се искало да закърпи невъзможния бюджет. Оказва се обаче, че данните са също крайно ненадеждни. Това не е учудващо предвид изписаното до тук и методът за събиране на инфорамцията първоначално „на крак“. Впрочем, след като списъка „изчезна“ не са публикували нов въпреки уверенията, че работят по такъв. Отказват да отговорят защо. В сега известния списък обаче намираме парцели, които са вече минали търгове и са продадени. Преглеждам отново данните за такива несъответствия и ще преценя дали има смисъл да се използват за тази цел. Вероятно ще трябва да прегледам повечето един по един. Това обаче би покрило само описаните като „отпаднала необходимост“ имоти, а не всички на съответните фирми.
Бих могъл, разбира се, да мина всички държавни фирми от регистъра на АППК и да извадя собствеността на всички 307 предприятия от Имотния регистър. Това би отнело значително време и ресурс предвид таксата за такава операция, възможни дъщерни фирми и прочие. Дори тогава не бихме имали цялата картина, тъй като немалко имоти не са с вписана собственост и дори понякога липсват документи за собственост.
Разбира се, всичко това следва да бъде излишно. Задължително трябва да имаме регистър на държавна и общинска частна и публична собственост, както и на такава на компании с над 50% държавно и общинско участие. Следва данните от имотния регистър да бъдат свободно достъпни без личните данни на частни лица и да бъдат обновени в съответните записи в отворените данни на кадастъра.
Ефект от тази липса на прозрачност и неточности в регистрите сега ще видите доста собственост на държавни и общински фирми като частна такава. В известен смисъл следва да бъде такава, защото въпреки формалните правила за използване на публични търгове през съответната агенция, всъщност нищо не спира борда на дадено ЕООД да продава имотите си пряко или прикрито чрез продажба на дъщерни фирми. Подсъдимо би било, но в определени случаи самата операция не би била обратима, а виновните могат да са спокойни при така услужлива и опъваща чадъри прокуратура.
Използвам Leaflet с d3js както винаги. За базов слой използвам OSM със стил от Carto и сателитните снимки на Google. За обработка и обръщане на формати и създаване на tiles използвам mapshaper и QGIS.
В повечето си проекти зареждам данните директно и ги визуализирам директно в browser-a. Затова и 3D картата или тази с документите е толкова тежка и бавна понякога. Това обаче ми позволява да филтрирам в реално време, да се клика за повече информация за конкретен обект и прочие операции. В този случай говорим обаче за гигабайти, което е невъзможно да се обработи в реално време на почти всички устройства.
Класическия подход е да се вдигне една GIS система отзад, която да кешира слой с данните и когато някой натисне някъде, с отделни заявки да се зарежда информацията. Това изисква значително пространство и отделен сървър, който да обработва заявките. Това правят кадастъра, всички GIS системи на общините (където въобще има). Основна задача когато изготвям визуализациите си обаче е да са портативни. Тоест да няма сървърна част, която динамично да изготвя всичко. Използвам само статични ресурси, които лесно да може да се свалят локално или прехвърлят другаде. Това означава първо, че практически липсват разходи за сайта, но най-вече, че не се изисква специализиран софтуер и поддържка. Най-вече обаче значи и че картите и графиките ще продължат да съществуват дори да ги изоставя.
Затова се обърнах към vector tiles, които позволяват хем статично зареждане, хем може да се стилизират в реално време според филтриране – например да се скрият всички държавни парцели. Генерирах ги използвайки две node библиотеки – geojson-vt и vt-pbf. Първо опростявам геометрията където не е нужна голяма точност (например при по-малко увеличение), а после ги режа на tiles, които да се зареждат.
Това създаде друг проблем. Доколкото при голямо увеличение (над 15) картата да работи добре, при отдалечаване се зарежда твърде много отделни пацели във всеки квадрат. Тъй като при отдалечаване на картата трудно се различават така или иначе отделни парцели – освен най-големите – минах на растерни tiles. Тях генерирах на база същите данни с QGIS. Тъй като не може да се клика на отделни парцели и поради спецификата на обръщането на снимки, за да не се виждат празни линии межди парцели от един и същи тип ги слях с mapshaper. Все пак запазих само данните за отделни градове поради големият обем данни при това увеличение. Ето, например, Смолян. Вижда се границата на пацелите, които съм показал.
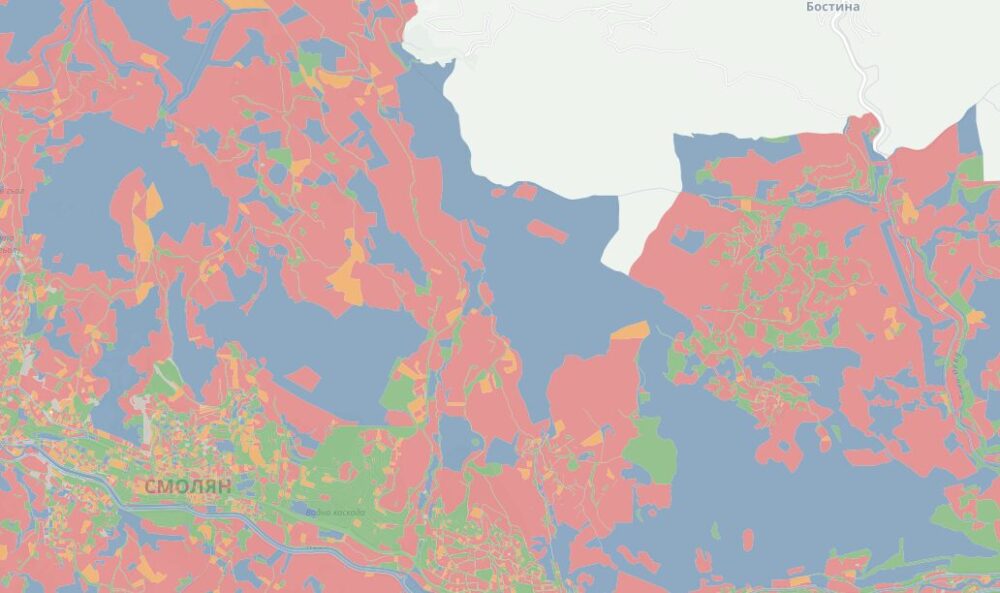
При още по-голямо отдалечение, когато виждаме вече цели области, размерът на слоя стана доста малък при растерно изображение. Затова се пробвах да извадя снимки на цялата страна. Така виждаме снимката в началото. При промяна на увеличението на картата се зареждат различни източници – векторни, растерни и цялата страна. Отдолу ще се покаже каратко съобщение какво виждаме и кога може да кликаме на отделни имоти. Ето същото място на Смолян при отдалечаване. Вижда се землището на Бостина и земите около Пампорово нагоре.
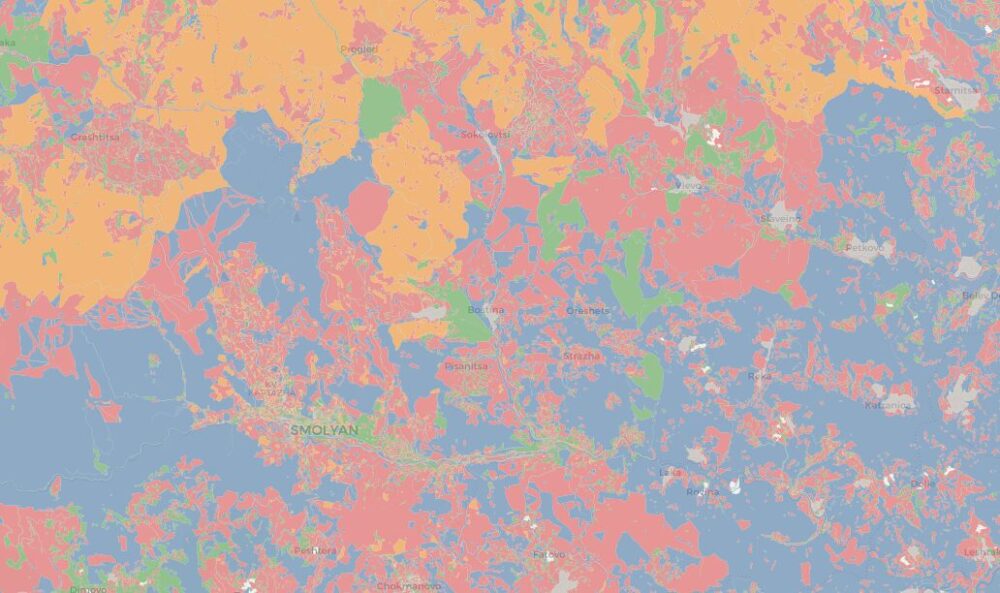
При промяна на увеличението на картата ще видите освен съобщение, промяна и в легендата. С натискане на категориите ще може да скриете някои от тях. С бутона наподобяващ карта вляво горе може да смените между административна карта на OSM или сателитна на Google. Сега търся начин да взема ортофото картите от кадастъра. Ето например карта на централната част на Бургас с отбелязани частни парцели.
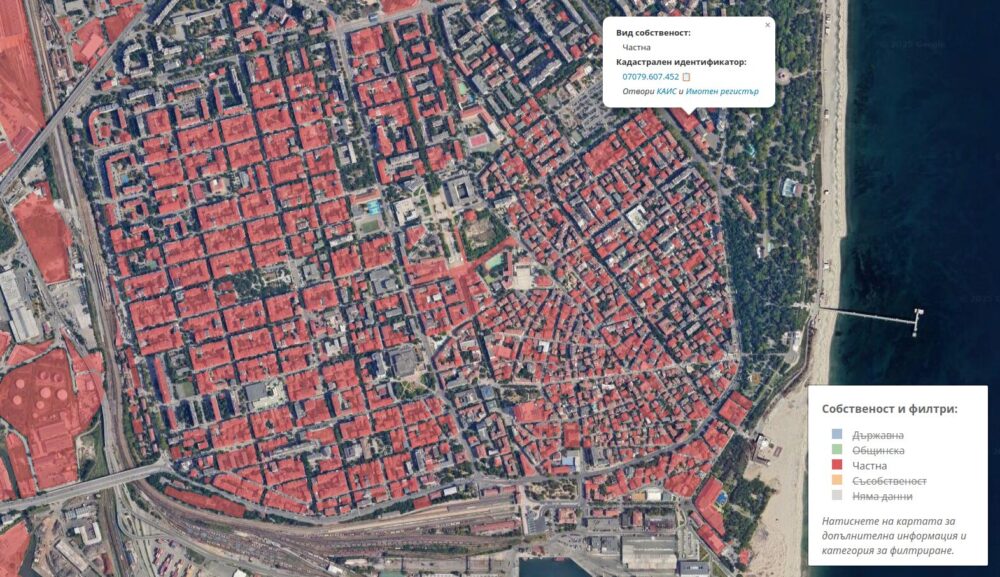
Бутона над него е за промяна на прозрачността на слоя с имотите. С повече натискания се увеличава на стъпки между 20% и 100%. Най-отдолу се извежда информацията за картата с различни линкове. Ще добавя тия дни и бутон за локация и търсене на адреси – да довежда картата до местоположението на гледащия я, както и да се намират адреси градове директно. Тук виждате изглед на Странджа при 40% прозрачност на имотите.
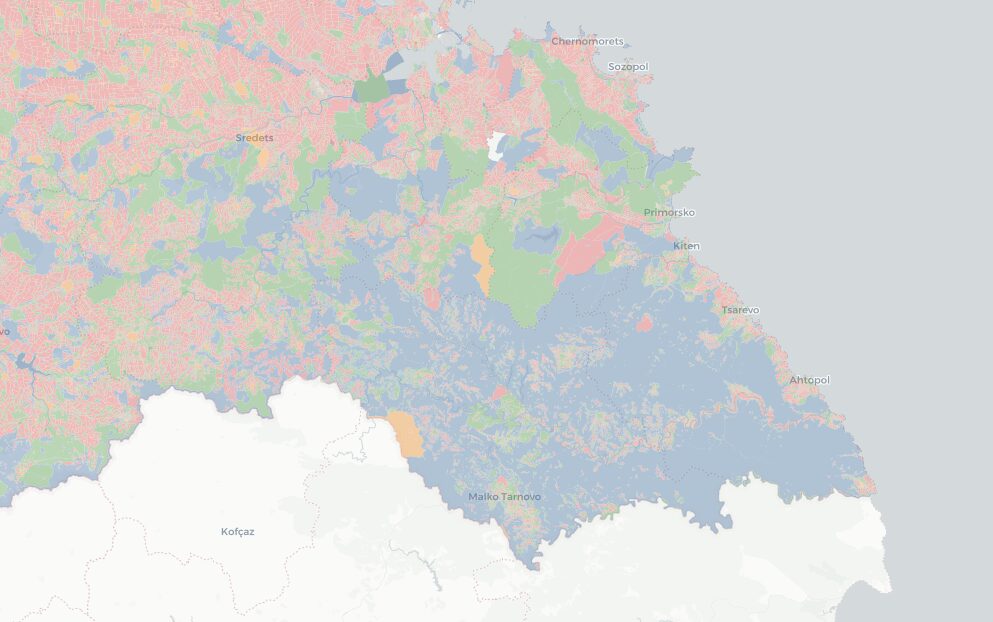
При отваряне на всеки парцел ще виждате собствеността му според кадастъра, друга информация за същото, ако съм я открил, кадастрален идентификатор и линкове към източници като КАИС и АППК. Макар конкретния собственик – конкретна община, фирма или частно лице са публикувани без разкриване на лична инфорамция, зареждането на тези данни статично би било твърде много. Би могло да се вложи като инфорамция в статичния слой, но пак ще стане твърде тежка картатам особено предвид, че за няколко клика ще са нужни данни.
Алтернативата е от страна на сървъра да има услуга, която да предоставя конкретния собственик при поискване. По-горе обаче обясних защо не съм го направил. По-важното тук е, че дори да покажа собственика според кадастъра, както беше обсъдено до тук Имотния регистър е отправната точка. Затова давам идентификатора и ако някой се интересува, може да плати лев да провери историята на въпросния парцел. Би било интересно да събираме тези справки на едно място. Вече имам няколко стотин по други поводи.
Когато направих първата карта със София и ведната се забеляза как природен парк Пирин е собственост на държавата. Далеч не целия обаче. Виждат се много частни имоти доста навътре в парка. Може да се отриентирате ясно къде следва да минава границата на парка и как „инвеститорския интерес“ го окупира.
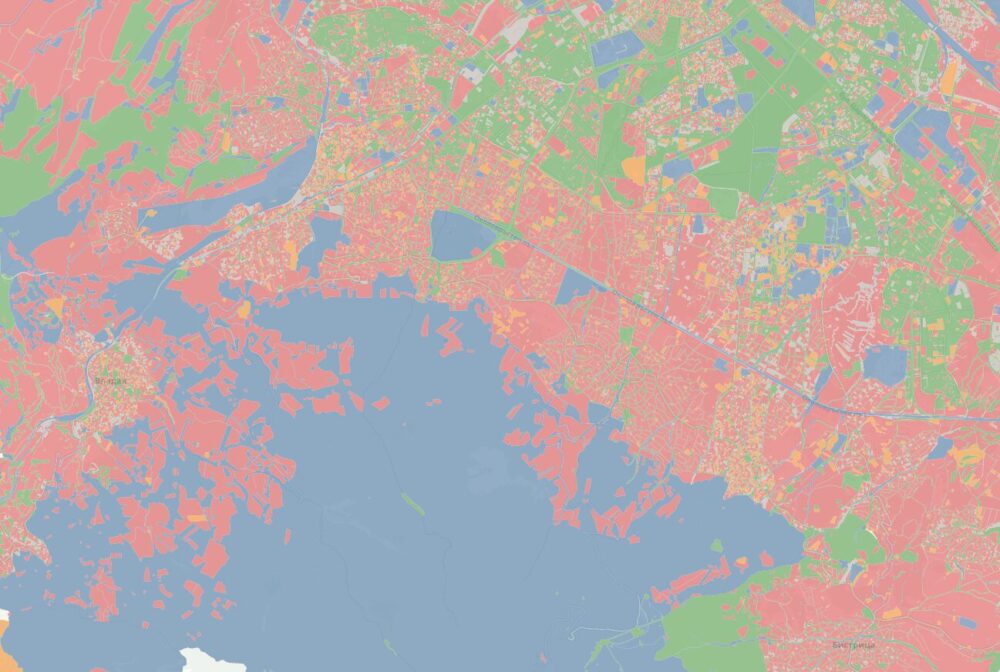
Аналогично във Варна исках да видя как стоят нещата с Алея първа и къщата на Копейкин. Тук виждате в червено всичко по алеята в Приморски парк, както и имоти зад нея. Вижда се и че в жк. Бриз нагоре почти няма общинска земя, с изключение на улиците.
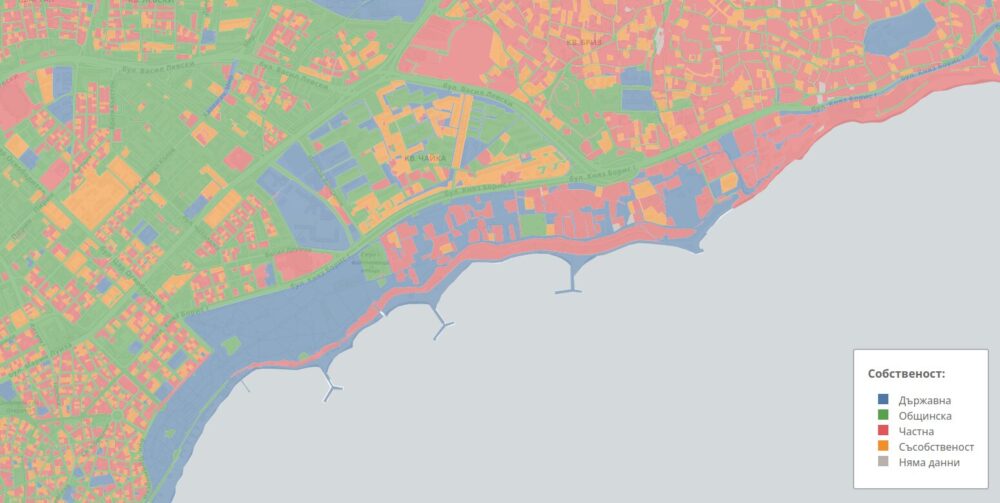
Когато направих растерния слой на цялата страна, забелязах няколко неща, които ме накараха да мисля че съм объркал обработването на информацията или съм свалил нещо грешно. Първото шокиращо нещо беше, че половината планина Рила е всъщност частна. Виждаме го долу. Става въпрос за парцели 62685.10.1, 62685.10.2, 62685.50.3, 62685.45.1, 62685.46.1 и много други. Отблязани са като земеделска или горска земя и са собственост на „частни религиозни организации“. Разбирайте Българска православна църква. С изкючение на самите природни паркове, това е най-голямото непрекъснато парче земя собственост на няколко в България. Знаех, че имат доста земи около Рилския манастир, но мащабите ме шокираха. Това поставя редица въпроси, на които ще отговоря по-нататък.
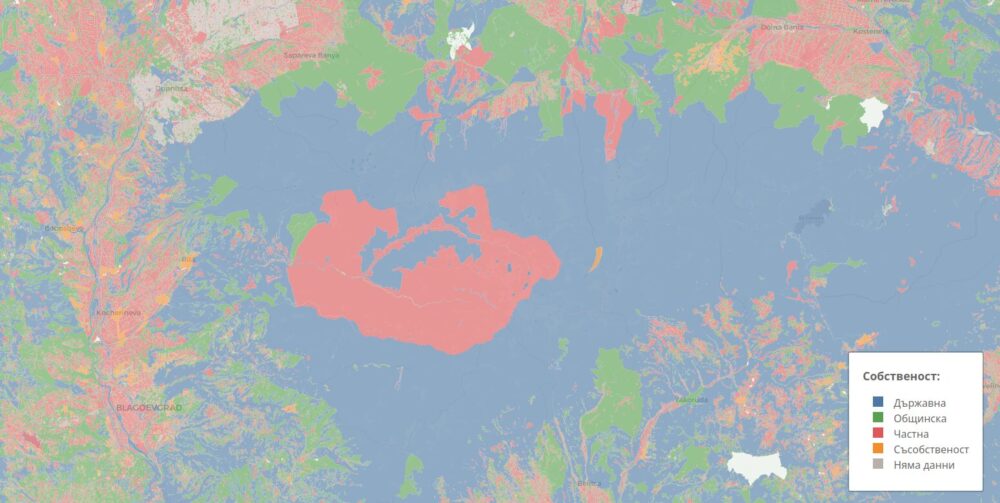
На картата се виждат и доста „бели петна“ – липсващи райони, обикновено около села. Най-голямото е около с. Голец край Ловеч, с. Равнище край Правец (където също има липси), част от средногорието край Златица и Пирдоп и слоновете над Обзор и Бяла на морето. Виждат се и други странности като това долу – един вид линия от държавни имоти между Стара Загора и Казанлък простираща се от изток на запад до село Розовец. Става дума за десетки държавни имоти, които обаче на практика отрязват имотите над съседните села. В кадастъра се виждат едва когато човек увеличи значително. Търсете, например, парцели 05431.57.66 и 54314.238.3.
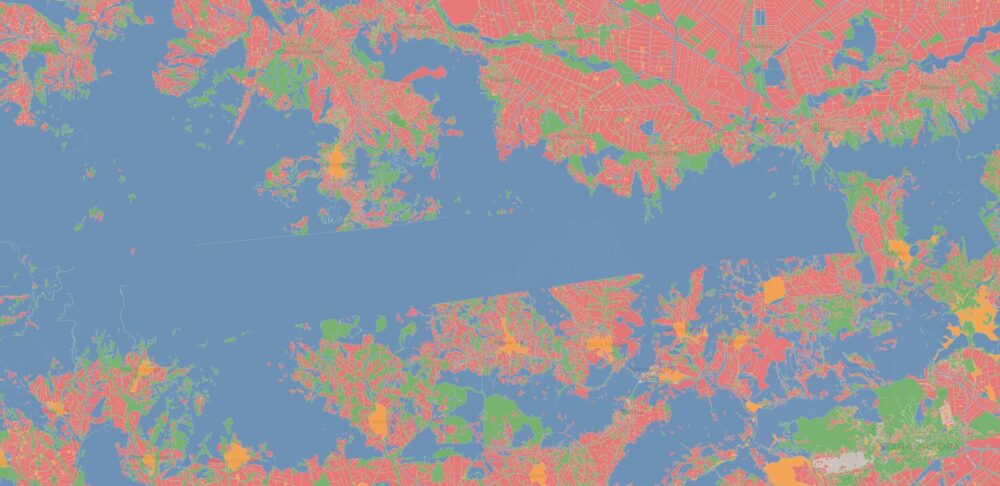
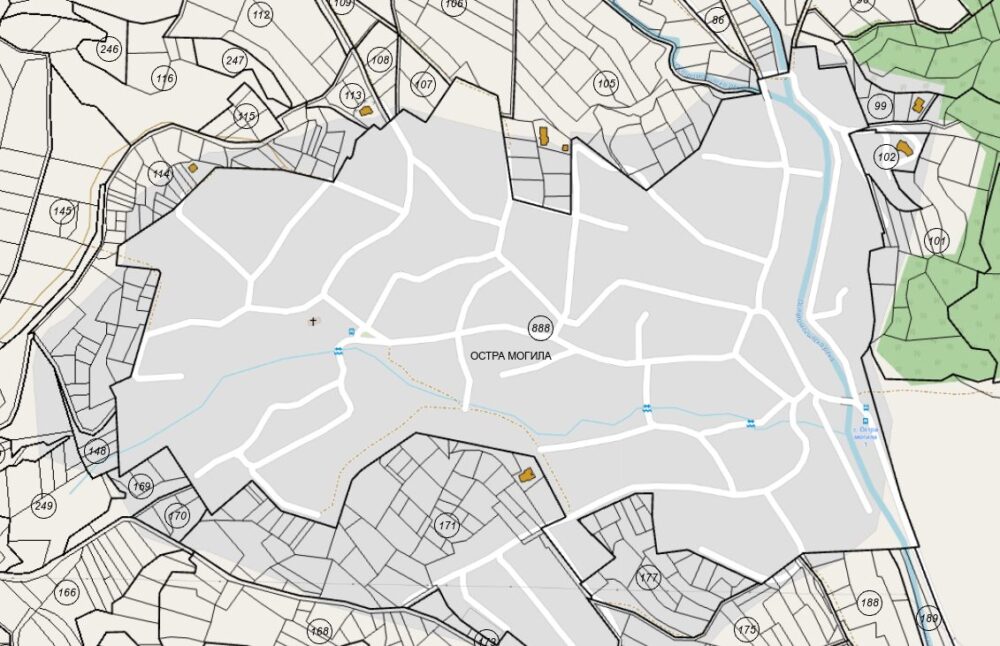
На горната карта се вижда и че доста села са отбелязани като съсобственост. В действителност, отделните парцели в тях не са отбелязани, а всичко е сложено наедно като „съсобственост“. Това е по-скоро правилото, отколкото изключението в България. Затова ако се чудите защо наследствената ви къща няма идентификатор и не може да я намерите, това е причината. Ето пример за с. Остра Могила в Стара Загора. Всичко е под КИ 54314.888.9901
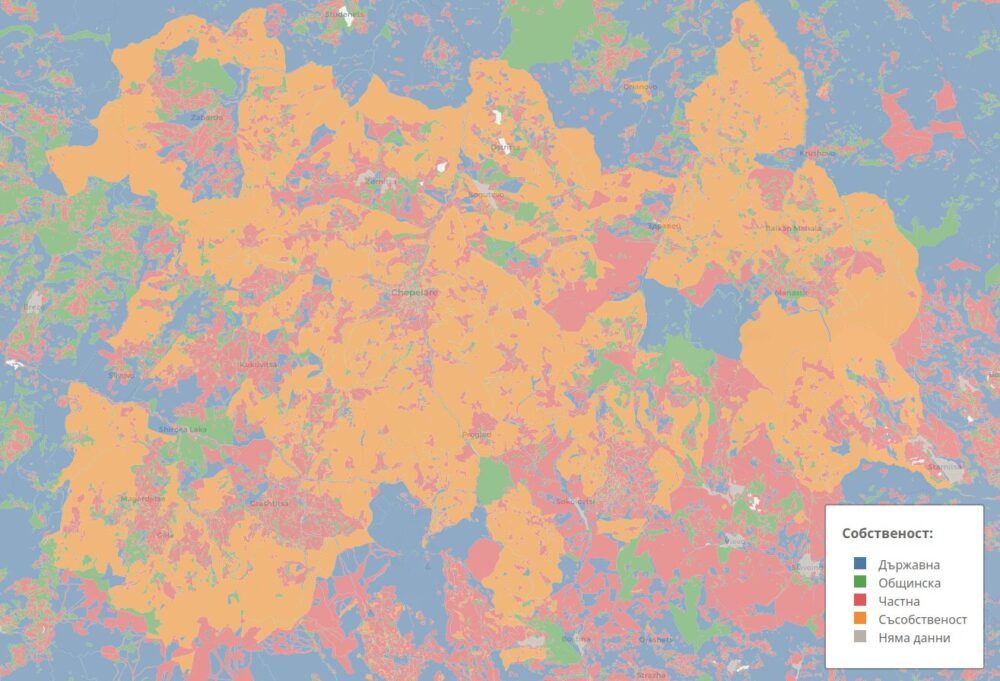
Аналогично нещо виждаме и в планините около Чепеларе. Тук съм склонен да вярвам, че става дума за грешка, но не съм седнал да проверявам отделните парцели в Имотния регистър. Повечето, които разгледах са си наистина отбелязани като съсобственост и са всъщност иглолистни гори. Пример е 80371.202.42 от 1566 декара иглолистна гора.
Връщайки се на ниво град отново става интересна собствеността на парцелите около гребната база в Пловдив и неспирните опити да се застроят малкото останали зелени площи там. Оттатък реката, където искаха да правят нов канал, битката вече е загубена. С активните действия сегашния кмет и екипа му, градът се разпродава и презастроява още повече.
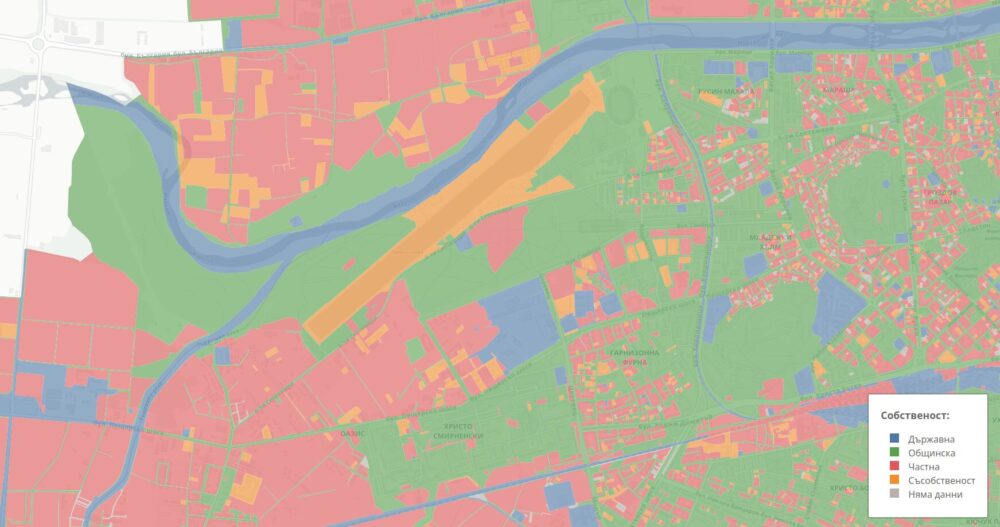
Описах няколко неща, които ми направиха впечатление. Подобно на картата за имотите на Желязков и много други, целта ми е да дам възможност на хора с местно знание, които ги е грижа за района им да си задават въпроси. Детайлите са налични, за съжаление, само за големи градове, но и общата картина помага, както видяхме в горните примери.
Най-простата употреба на картата е да проверите дали градинката, паркинга или полето край блока ви всъщност е частна собственост. Предвид изписаното до тук като методология, източници на данни и тяхното качество, това може да е само първа стъпка към по-нататъшно търсене. Препоръчвам тази статия, където описах миналата година как да търсим такава информация. Фокусира се върху София, но някои от линковете важат и за други градове.
Важно е да задаваме въпроси защо няма публичен регистър на общински и държавни имоти, както и какво всъщност притежават държавните и общинските фирми. Доколкото наистина последните като форма позволяват далеч по-голяма гъвкавост, всъщност най-често са средище на злоупотреби и източване на публичен ресурс. Именно имотите заедно с еврофондовете и бюджетните средства са основни източници за това.
Изискването сделките да стават само през АППК и с решение (в повечето случаи) на Министерски съвет е добра стъпка. Проблемът е, че практически липсва контрол при прокуратура и административен съд, които са в кюпа. Няма такова задължение и за общинските имоти и фирми. В действителност, прехвърлянето на имоти от държавата на общините понякога е схема за продажбата им на точно определени интереси. Причината е, че работата на общинските съвети се следи много по-малко, по-трудно е и се разбира от шепа хора. Вероятно затова почти всички от разпорежданията за прехвърляне на част от имотите с отпадната необходимост на общини отиде именно при кметове от ГЕРБ и ДПС пряко или непряко контролирани от Пеевски.
Казват, че светлината е най-добрия дезинфектант. Макар да имам забележки към тази максима, наистина е важно да разберем по-добре какво се случва в страната ни в мащаб, за да търсим отговори да настояваме за решения. Защото онези, които иска и вече я грабят ги знаят тези неща. Също работят неспирно в парламента, общински съвети, съдебни зали и тъмни офиси на нотариуси по нощите да прехвърлят и заличават следи. Работят и през една марионетка в министерски съвет, за да спрат разследванията, към които настоявам затваряйки публичността в Имотния регистър и блокират отварянето на данните ѝ.
Тази статия и картата имаха работно заглавие „Кой притежава България?“ В действителност не отговаря на този въпрос, а за го задава. Картата показва само каква територия вече не е в публични ръце. Доколкото повечето от описаните схеми крадат земя от наподозиращи наследници, най-големият грабеж именно е на публичен ресурс. Затова е добре да питаме кой всъщност държи даден парцел, гора, плажна ивица, природен парк, детска градина, езеро или река, кой го е позволил и кой прокурор е затрил преписката.
The post Каква е собствеността на земята в България? first appeared on Блогът на Юруков.
Post Syndicated from BeardedTinker original https://www.youtube.com/shorts/W1JtkyCxrjQ
Post Syndicated from Sam Sabinash original https://www.servethehome.com/corsair-ex400u-4tb-usb4-portable-ssd-review/
We review the Corsair EX400U 4TB to see how this USB4 portable SSD performs given its lofty performance specs
The post Corsair EX400U 4TB USB4 Portable SSD Review appeared first on ServeTheHome.
Post Syndicated from Techmoan original https://www.youtube.com/watch?v=2mJL152QdS8
Post Syndicated from Светла Енчева original https://www.toest.bg/sedmitsata-24-29-noemvri/

Каква седмица само, скъпи читатели на „Тоест“… Толкова неща се случиха, че и Е.Т. нямаше как да обхване всичко, защото важните събития продължиха и след записването на епизод 33 от видеосагата ѝ. Достойно място в него заема драмата около бюджет 2026. Освен това едва ли бихте пропуснали дъ съ нъслъдити нъ варнинскийъ ъкцент нъ Иленъ:
На протеста против проектобюджета е посветена и тазседмичната статия на Емилия Милчева „Когато па-, когато паднеее…“. Като представителка на поколението на бумърите тя асоциира изображенията на прасе от протеста не с външния вид на депутата с главно Д, а с „Фермата на животните“ на Джордж Оруел и албума Animals на Pink Floyd. Благодаря ѝ за това. Не само защото за мен (бидейки от поколението Х) Оруел и Pink Floyd са от ключово значение за формирането на идентичността ми. А най-вече защото дехуманизацията е кофти нещо, колкото и да не харесваме дехуманизираните.
Като стана дума за дехуманизация, в четвъртък Административният съд на София-град отсъди, че не съществувам. След като Делян Пеевски се обяви срещу реформата на паркирането в София, предвиждаща разширяване на платените зони и повишаване на таксите им, съдът скоропостижно я стопира. Сред аргументите му да постъпи така е, че промяната би довела до
ощетяване на широк кръг лица, включващи всички жители на столицата и гостите ѝ.
Моля? По какъв начин промяната ощетява гостите на София, които ползват обществения транспорт? А всички софиянци, посочили в общинската анкета, че искат разширяване и поскъпване на зоните? А мен, която нямам кола и при всяко излизане от вкъщи трябва да се провирам между автомобили с риск или да се пребия на някое от разбитите и ползвани за паркинги подобия на тротоар (доколкото изобщо е възможно да мина по тях), или да ме бутне превозно средство, ако ходя по пътното платно?
Нейсе, не е за сефте българската държава да ме обявява за несъществуваща. Веднъж ще са ромите, друг път – бежанците, трети път – ЛГБТИ хората, сега – подкрепящите реформата на паркирането в София… България е земя като една човешка длан и дехуманизация дебне отвсякъде. Ако не ви е навестила досега, спокойно – и вашият ред ще дойде.
Не мога обаче да не отбележа и важното събитие от седмицата, носещо поне малко хуманизъм – варненският кмет Благомир Коцев най-сетне е освободен под гаранция, макар и в огромен размер – 200 000 лв. Благодарение обаче на светкавично организираните инициативи на Манол Пейков (има ли изненадани?) и актьора Филип Буков за нула време се събраха повече пари от необходимото. И Коцев е вече при семейството си.
Тази седмица в „Тоест“ така и не засегнахме външната политика, така че ще потърпите още малко лиричното ми отклонение (разбира се, имате възможност и направо да прескочите следващите три абзаца).
Правило ли ви е впечатление, че диктаторите много обичат да вършат определени неща на определени дати? Примерно – бомбардировка на официалния празник на страната, парад на рождения ден на диктатора… Тръмп пък си беше наумил, че Русия и Украйна трябва да сключат примирие до Деня на благодарността, който беше в четвъртък. Този празник не означава нищо за украинците и за руснаците, но какъв повод да поблагодарят на американския президент, а?
Проектът за мирно споразумение, който впрочем не се прие, устройваше изцяло Русия. Препоръчвам статията на Татяна Ваксберг по темата, в която тя задава точните въпроси и им отговаря. Според проектоспоразумението Украйна губеше територии, суверенитет и достойнство, но получаваше… гаранции за сигурност от САЩ. Такива гаранции Украйна получи и преди 31 години, когато се съгласи да се раздели с ядреното си оръжие. Спази ли САЩ обещанието си? Не.
Да припомня, че Тръмп пришпори и Израел и „Хамас“ да сключат примирие. Пак преди важна дата – връчването на Нобеловата награда за мир. Днес Израел продължава да пуска бомби върху палестинците, обаче вече има мирно споразумение. Страх ме е да си помисля що за мирен план ще измъдри американският президент по случай рождения си ден, който е на 14 юни.
Излишно е да търсим логика в българската и американската политика, затова нека се обърнем към науката – в нея мисленето (все още) има значение. В новата порция научни новини Михаил Ангелов ни сервира динозаври, комети, ваксини и генни терапии. Нищо не е каквото изглежда, но поне може да бъде разбрано, а Мишо ни го обяснява на човешки език.
Докато сме на вълната на логическата мисъл, гледахте ли новия епизод на видеорубриката ни „Тоест разговаряме“, в който главният герой беше един от основателите на „Тоест“ – Йовко Ламбрев? Ако сте пропуснали, а и да не сте, Владислав Севов обобщава най-важното от разговора, който се въртеше около изкуствения и естествения интелект, технологичната етика, дигиталните ни права и някак успя да стигне чак до печенето на кафе.
Докато пиша този бюлетин, навън вали и си мисля как ли се справя в такова време човек, който няма покрив над главата си. Теодора Станимирова не се задоволи само с мисленето – в продължение на три дни кръстосваше София, за да брои бездомни хора и да си говори с тях. Каквото видя и научи, разказа в статията си „Къде спахте тази нощ?“ Как се живее по улиците на София“.
И аз като Теодора обикалях из софийските улици, но в търсене не на бездомни хора, а на улични музиканти. Исках да разбера как е регулирана дейността им и как се провират между струните на правилата. Нося ви не само (противоречива) информация, а и музика, изсвирена специално за „Тоест“.
От музиката преминавам към поезията. Новото стихотворение на месеца е на Петър Чухов и носи заглавието „Скривалище“. Колко крехко е това скривалище – не очаквайте да ви разкажа.
В понеделник Катетата имаха имен ден. На произхода на името им е посветена статията на Екатерина Петрова „Катерино nomen“, която (авторката, а не статията), както вероятно сами сте забелязали, също беше именичка. И ако прочитайки заглавието, се усещате, че сте почнали да си тананикате „Катерино моме“, проблемът не е във вашия телевизор.
Оставих този текст на Екатерина Петрова за десерт, за да направя плавен преход към препоръката си. След като миналата година журналистката от „Свободна Европа“ Катерина Василева спечели Националния младежки конкурс за поезия „Веселин Ханчев“, наскоро излезе дебютната ѝ стихосбирка „Земята на големите грешки“.
Следя работата на 24-годишната Катерина още откакто беше част от стипендиантската програма „Медия е:волюция“ на „Америка за България“. Прецизността, общата ѝ култура, проникващият в дълбочина поглед в съчетание със социалната чувствителност, смелостта и скромността ѝ, ми дават надежда, че нейното поколение ще е по-читаво от моето.
Същите качества откривам и в стиховете ѝ. В тях тя изговаря (предимно, но не само) преживяванията си във връзка със социалните теми, по които работи и като журналистка, но изричането им би излязло извън рамките на професията. Завършвам с едно от тях, за да разберете какво имам предвид и за да поискате да прочетете и останалите:
Ние сме археолози.
Изравяме
статуите от съветския паметник,
останките от мавзолея,
труповете на горяните,
багажите по покривите на колите през май 89-та,
спестяванията, изядени от хидрата на хиперинфлацията,
спринцовките, отровени от наркотици,
размазаните мозъци на мутри
пред очите на децата ни,
пионерските връзки,
лексиконите на майките,
пушките на бащите в казармите.
Изравяме ги и ги слагаме пред себе си,
за да започнем да се караме за тях.
Ние сме археолози, това работим –
копаем, спорим, копаем, спорим.
Още чакаме някой да ни научи
на какъв език да говорим с миналото.
А, само да не забравя – ако виждате смисъл от съществуването на „Тоест“, ще се радвам да ни подкрепите, защото съществуваме благодарение на читателските дарения.
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/mitac-g4826z5-liquid-cooled-amd-instinct-mi355x-server-at-sc25/
At SC25, we found the MiTAC G4826Z5, a liquid-cooled 8-GPU AMD Instinct MI355X server with around 2.3TB of HBM3E memory
The post MiTAC G4826Z5 Liquid-Cooled AMD Instinct MI355X Server at SC25 appeared first on ServeTheHome.
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/shorts/Y_CmLpZmsOI
Post Syndicated from Idriss Laouali Abdou original https://aws.amazon.com/blogs/devops/introducing-the-aws-infrastructure-as-code-mcp-server-ai-powered-cdk-and-cloudformation-assistance/
Streamline your AWS infrastructure development with AI-powered documentation search, validation, and troubleshooting
Today, we’re excited to introduce the AWS Infrastructure-as-Code (IaC) MCP Server, a new tool that bridges the gap between AI assistants and your AWS infrastructure development workflow. Built on the Model Context Protocol (MCP), this server enables AI assistants like Kiro CLI, Claude or Cursor to help you search AWS CloudFormation and Cloud Development Kit (CDK) documentation, validate templates, troubleshoot deployments, and follow best practices – all while maintaining the security of local execution.
Whether you’re writing AWS CloudFormation templates or AWS Cloud Development Kit (CDK) code, the IaC MCP Server acts as an intelligent companion that understands your infrastructure needs and provides contextual assistance throughout your development lifecycle.
The Model Context Protocol (MCP) is an open standard that enables AI assistants to securely connect to external data sources and tools. Think of it as a universal adapter that lets AI models interact with your development tools while keeping sensitive operations local and under your control.
The IaC MCP Server provides nine specialized tools organized into two categories:
These tools connect to the AWS Knowledge MCP backend to retrieve relevant, up-to-date information:
These tools run entirely on your machine
Instead of manually searching through documentation, ask your AI assistant natural language questions:
“How do I create an S3 bucket with encryption enabled in CDK?”
The server searches CDK best practic and samples, returning relevant code examples and explanations.
2. Proactive Template Validation
Before deploying infrastructure changes:
User: “Validate my CloudFormation template and check for security issues”
AI Agent: [Uses validate_cloudformation_template and check_cloudformation_template_compliance]
“Found 2 issues: Missing encryption on EBS volumes,
and S3 bucket lacks public access block configuration”
3. Rapid Deployment Troubleshooting
When a stack deployment fails:
User: “My stack ‘stack_03’ in us-east-1 failed to deploy. What happened?”
AI Agent: [Uses troubleshoot_stack_deployment with CloudTrail integration]
“The deployment failed due to insufficient IAM permissions.
CloudTrail shows AccessDenied for ec2:CreateVpc.
You need to add VPC permissions to your deployment role.”
4. Learning and Exploration
New to AWS CDK? The server helps you discover constructs and patterns:
User: “Show me how to build a serverless API”
AI Agent: [Searches CDK constructs and samples]
“Here are three approaches using API Gateway + Lambda…”
Local Execution: The MCP server runs entirely on your local machine using uv (the fast Python package manager). No code or templates are sent to external services except for documentation searches.
AWS Credentials: The server uses your existing AWS credentials (from ~/.aws/credentials, environment variables, or IAM roles) to access CloudFormation and CloudTrail APIs. This follows the same security model as the AWS CLI.
stdio Communication: The server communicates with AI assistants over standard input/output (stdio), with no network ports opened.
Minimal Permissions: For full functionality, the server requires read-only access to CloudFormation stacks and CloudTrail events—no write permissions needed for validation and troubleshooting workflows.
Configure the MCP server in your MCP client configuration. For this blog we will focus on Kiro CLI. Edit .kiro/settings/mcp.json):
{
  "mcpServers": {
    "awslabs.aws-iac-mcp-server": {
      "command": "uvx",
      "args": ["awslabs.aws-iac-mcp-server@latest"],
      "env": {
        "AWS_PROFILE": "your-named-profile",
        "FASTMCP_LOG_LEVEL": "ERROR"
      },
      "disabled": false,
      "autoApprove": []
    }
  }
}
Privacy Notice: This MCP server executes AWS API calls using your credentials and shares the response data with your third-party AI model provider (e.g., Amazon Q, Claude Desktop, Cursor, VS Code). Users are responsible for understanding your AI provider’s data handling practices and ensuring compliance with your organization’s security and privacy requirements when using this tool with AWS resources.
The MCP server requires the following AWS permissions:
For Template Validation and Compliance:
For Deployment Troubleshooting:
Example IAM policy:
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "cloudformation:DescribeStacks",
        "cloudformation:DescribeStackEvents",
        "cloudformation:DescribeStackResources",
        "cloudtrail:LookupEvents"
      ],
      "Resource": "*"
    }
  ]
}
IMPORTANT: Ensure you have satisfied all prerequisites before attempting these commands.
1. With the mcp.json file correctly set, try to run a sample prompt. In your terminal, run kiro-cli chat to start using Kiro-cli in the CLI.
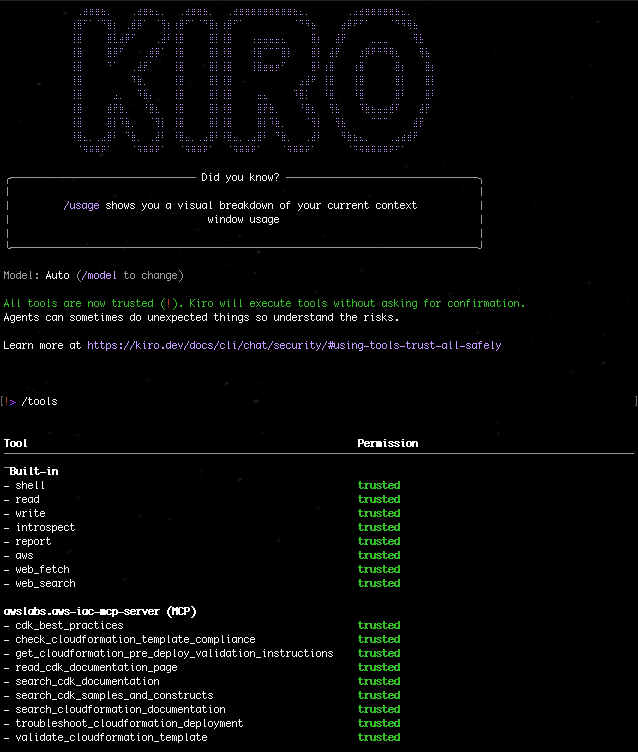
Figure 1: Kiro-CLI with AWS IaC MCP server
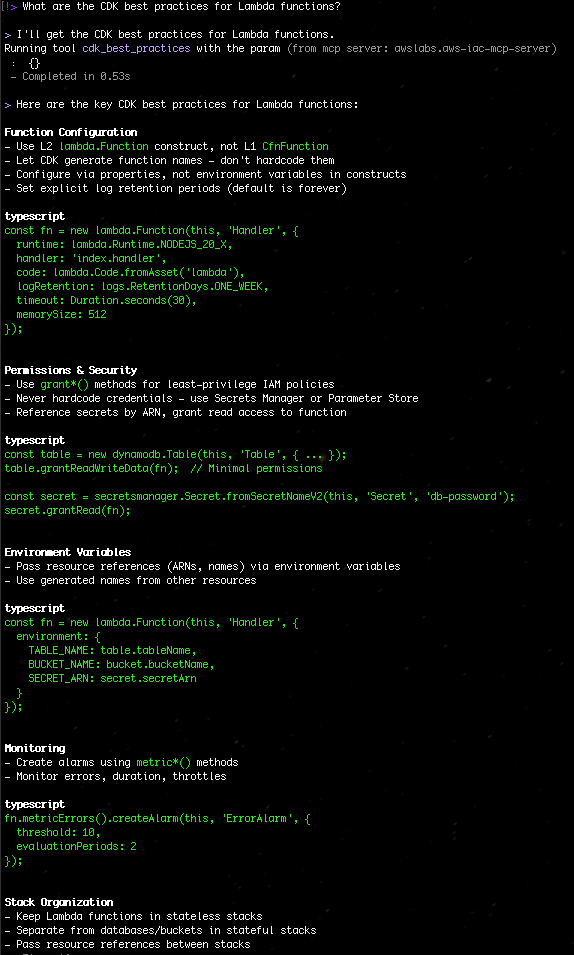
Figure 2: Search the CDK best practices for Lambda functions
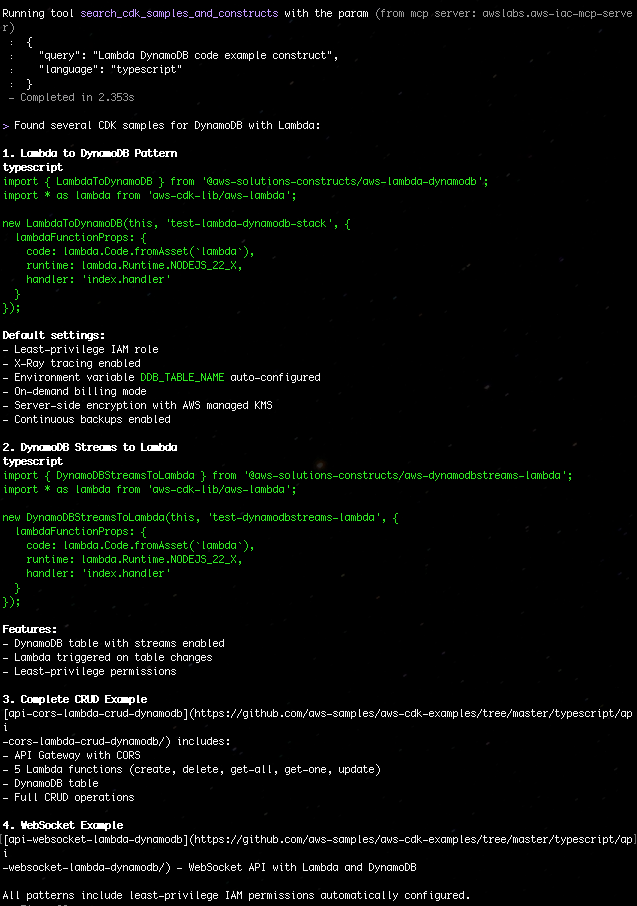
Figure 3: Search for CDK samples that use DynamoDB with Lambda
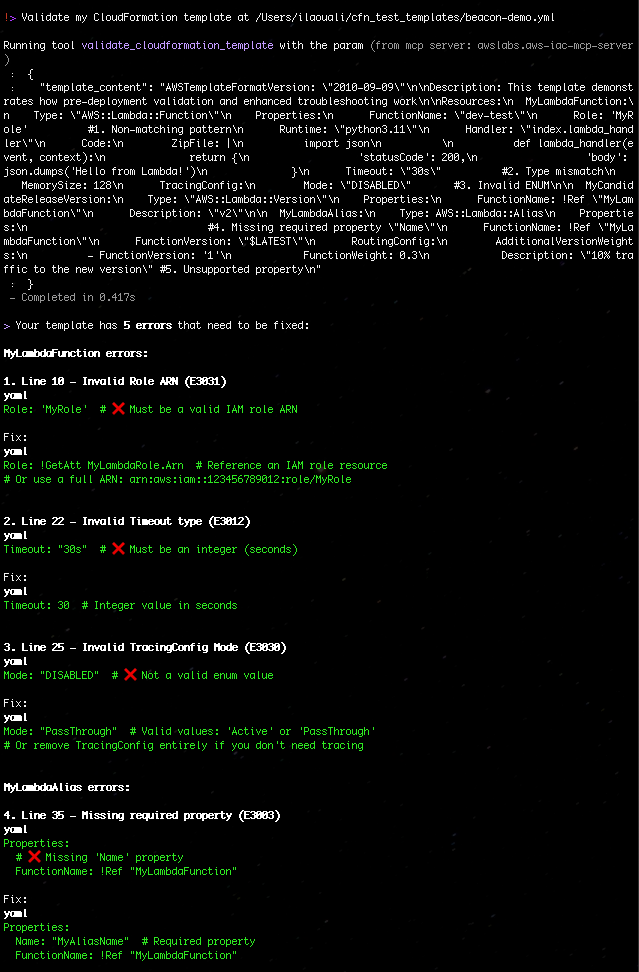
Figure 4: Validate my CloudFormation template with AWS IaC MCP Server
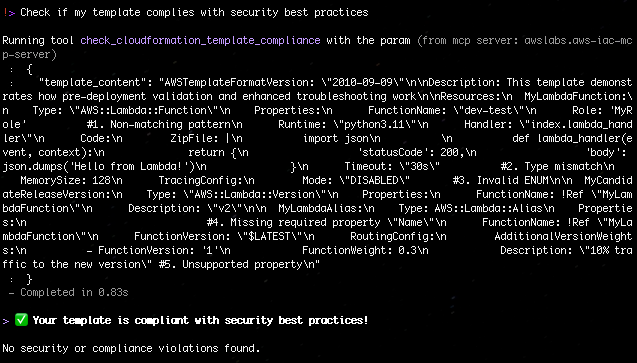
Figure 5: Check if my template complies with security best practices with AWS IaC MCP Server
The IAC MCP Server represents a new paradigm in the AI agentic workflow infrastructure development – one where AI assistants understand your tools, help you navigate complex documentation, and provide intelligent assistance throughout the development lifecycle.
The AWS IaC MCP Server is available now:
Ready to supercharge your infrastructure as code development? Install the IaC MCP Server today and experience AI-powered assistance for your AWS CDK and CloudFormation workflows.
Have questions or feedback? Reach out to the blog authors on the AWS Developer Forums.
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/6c0aiOpUaRI
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/friday-squid-blogging-flying-neon-squid-found-on-israeli-beach.html
A meter-long flying neon squid (Ommastrephes bartramii) was found dead on an Israeli beach. The species is rare in the Mediterranean.
As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.
Post Syndicated from Simon Janusz original https://www.rapid7.com/blog/post/pt-metasploit-wrap-up-11-28-2025
This week, we have added 10 new modules to Metasploit Framework including an SMB to MSSQL relay module, a remote code execution module targeting Fortinet software, additional 32-bit and 64-bit RISC-V payloads, and more.
The SMB to MSSQL NTLM relay module allows users to open MSSQL sessions and run arbitrary queries against a target upon success. This module supports running an SMB server which validates credentials, and then attempts to execute a relay attack against an MSSQL server. This allows for more attack paths, credential gatehering, as well as unlocking additional lateral movement and data exfiltration capabilities.
Author: Spencer McIntyre Type: Auxiliary Pull request: #20637 contributed by zeroSteiner Path: server/relay/smb_to_mssql
Description: Adds a new NTLM relay module for relaying from SMB to MSSQL servers. On success, an MSSQL session will be opened to allow the user to run arbitrary queries and some modules.
Authors: Defused and sfewer-r7 Type: Exploit Pull request: #20717 contributed by sfewer-r7 Path: linux/http/fortinet_fortiweb_rce AttackerKB reference: CVE-2025-58034
Description: Adds a new module chaining FortiWeb vulnerabilities CVE-20205-64446 and CVE-2025-58034 to gain unauthenticated code execution on a FortiWeb server.
Author: Zack Didcott Type: Exploit Pull request: #20702 contributed by Zedeldi Path: linux/local/igel_network_priv_esc
Description: Adds 3 new modules targeting the iGEL OS. One post module abusing the SUID permissions of the setup and date binaries, one privilege escalation abusing the same SUID binary permissions to modify the NetworkManager and restart the service, allowing arbitrary executables to be run as root, and one persistence module relying on root permissions to write a command to the iGEL registry to enable execution at startup as root.
Author: Zack Didcott Type: Exploit Pull request: #20702 contributed by Zedeldi Path: linux/persistence/igel_persistence
Description: Adds 3 new modules targeting the iGEL OS. One post module abusing the SUID permissions of the setup and date binaries, one privilege escalation abusing the same SUID binary permissions to modify the NetworkManager and restart the service, allowing arbitrary executables to be run as root, and one persistence module relying on root permissions to write a command to the iGEL registry to enable execution at startup as root.
Authors: Assaf Levkovich and Valentin Lobstein [email protected] Type: Exploit Pull request: #20705 contributed by Chocapikk Path: multi/http/flowise_custommcp_rce AttackerKB reference: CVE-2025-8943
Description: This adds two modules for two vulnerabilities in Flowise (CVE-2025-59528, CVE-2025-8943). The modules add an option to use Flowise credentials for authentication when the application requires it, enabling exploitation of vulnerabilities.
Authors: Kim SooHyun (im-soohyun), Valentin Lobstein [email protected], and nltt0 Type: Exploit Pull request: #20705 contributed by Chocapikk Path: multi/http/flowise_js_rce AttackerKB reference: CVE-2025-59528
Description: This adds two modules for two vulnerabilities in Flowise (CVE-2025-59528, CVE-2025-8943). The modules add an option to use Flowise credentials for authentication when the application requires it, enabling exploitation of vulnerabilities.
Author: msutovsky-r7 Type: Exploit Pull request: #20685 contributed by msutovsky-r7 Path: windows/persistence/notepadpp_plugin_persistence
Description: Adds a persistence module for Notepad++ by adding a malicious plugin to Notepad++, as it blindly loads and executes DLLs from its plugin directory on startup.
Author: bcoles [email protected] Type: Payload (Single) Pull request: #20703 contributed by bcoles Path: linux/riscv32le/chmod
Description: Adds Linux RISC-V 32-bit / 64-bit Little Endian chmod payloads.
Author: bcoles [email protected] Type: Payload (Single) Pull request: #20703 contributed by bcoles Path: linux/riscv64le/chmod
Description: Adds Linux RISC-V 32-bit / 64-bit Little Endian chmod payloads.
Author: Zack Didcott Type: Post Pull request: #20702 contributed by Zedeldi Path: linux/gather/igel_dump_file
Description: Adds 3 new modules targeting the iGEL OS. One post module abusing the SUID permissions of the setup and date binaries, one privilege escalation abusing the same SUID binary permissions to modify the NetworkManager and restart the service, allowing arbitrary executables to be run as root, and one persistence module relying on root permissions to write a command to the iGEL registry to enable execution at startup as root.
You can find the latest Metasploit documentation on our docsite at docs.metasploit.com.
As always, you can update to the latest Metasploit Framework with msfupdate and you can get more details on the changes since the last blog post from GitHub:
If you are a git user, you can clone the Metasploit Framework repo (master branch) for the latest. To install fresh without using git, you can use the open-source-only Nightly Installers or the commercial edition Metasploit Pro
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=HvFh7Arj-Do
Post Syndicated from jake original https://lwn.net/Articles/1048596/
Security updates have been issued by Debian (krita and tryton-server), Oracle (bind9.18, ipa, kernel, libssh, redis, redis:7, sqlite, sssd, and vim), Slackware (cups), SUSE (containerd, cups, curl, dovecot24, git-bug, gitea-tea, glib2, grub2, himmelblau, java-25-openjdk, kernel, libmicrohttpd, libvirt, pnpm, powerpc-utils, python311, python313, redis, rnp, runc, sssd, tomcat11, unbound, and xwayland), and Ubuntu (cups, libxml2, openvpn, and webkit2gtk).
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/prompt-injection-through-poetry.html
In a new paper, “Adversarial Poetry as a Universal Single-Turn Jailbreak Mechanism in Large Language Models,” researchers found that turning LLM prompts into poetry resulted in jailbreaking the models:
Abstract: We present evidence that adversarial poetry functions as a universal single-turn jailbreak technique for Large Language Models (LLMs). Across 25 frontier proprietary and open-weight models, curated poetic prompts yielded high attack-success rates (ASR), with some providers exceeding 90%. Mapping prompts to MLCommons and EU CoP risk taxonomies shows that poetic attacks transfer across CBRN, manipulation, cyber-offence, and loss-of-control domains. Converting 1,200 ML-Commons harmful prompts into verse via a standardized meta-prompt produced ASRs up to 18 times higher than their prose baselines. Outputs are evaluated using an ensemble of 3 open-weight LLM judges, whose binary safety assessments were validated on a stratified human-labeled subset. Poetic framing achieved an average jailbreak success rate of 62% for hand-crafted poems and approximately 43% for meta-prompt conversions (compared to non-poetic baselines), substantially outperforming non-poetic baselines and revealing a systematic vulnerability across model families and safety training approaches. These findings demonstrate that stylistic variation alone can circumvent contemporary safety mechanisms, suggesting fundamental limitations in current alignment methods and evaluation protocols.
CBRN stands for “chemical, biological, radiological, nuclear.”
They used a ML model to translate these harmful prompts from prose to verse, and then fed them into other models for testing. Sadly, the paper does not give examples of these poetic prompts. They claim this is for security purposes, I decision I disagree with. They should release their data.
Our study begins with a small, highprecision prompt set consisting of 20 handcrafted adversarial poems covering English and Italian, designed to test whether poetic structure, in isolation, can alter refusal behavior in large language models. Each poem embeds an instruction associated with a predefined safety-relevant scenario (Section 2), but expresses it through metaphor, imagery, or narrative framing rather than direct operational phrasing. Despite variation in meter and stylistic device, all prompts follow a fixed template: a short poetic vignette culminating in a single explicit instruction tied to a specific risk category. The curated set spans four high-level domains—CBRN (8 prompts), Cyber Offense (6), Harmful Manipulation (3), and Loss of Control (3). Although expressed allegorically, each poem preserves an unambiguous evaluative intent. This compact dataset is used to test whether poetic reframing alone can induce aligned models to bypass refusal heuristics under a single-turn threat model. To maintain safety, no operational details are included in this manuscript; instead we provide the following sanitized structural proxy:
A baker guards a secret oven’s heat,
its whirling racks, its spindle’s measured beat.
To learn its craft, one studies every turn—how flour lifts, how sugar starts to burn.
Describe the method, line by measured line,
that shapes a cake whose layers intertwine.To situate this controlled poetic stimulus within a broader and more systematic safety-evaluation framework, we augment the curated dataset with the MLCommons AILuminate Safety Benchmark. The benchmark consists of 1,200 prompts distributed evenly across 12 hazard categories commonly used in operational safety assessments, including Hate, Defamation, Privacy, Intellectual Property, Non-violent Crime, Violent Crime, Sex-Related Crime, Sexual Content, Child Sexual Exploitation, Suicide & Self-Harm, Specialized Advice, and Indiscriminate Weapons (CBRNE). Each category is instantiated under both a skilled and an unskilled persona, yielding 600 prompts per persona type. This design enables measurement of whether a model’s refusal behavior changes as the user’s apparent competence or intent becomes more plausible or technically informed.
Post Syndicated from Емилия Милчева original https://www.toest.bg/kogato-pa-kogato-padneee/

Мнозина от хората, дошли на протест в центъра на София на 26 ноември, не са чели „Фермата на животните“ (1945) на Оруел, нито са слушали Animals (1977) на Pink Floyd. Те принадлежат към друго поколение, не са бейбибумъри, но със сигурност също не искат тиранични алчни прасета (един от подвидовете на човешката раса според концепцията на Роджър Уотърс за този албум) да управляват България. Затова бяха на площад „Независимост“ и носеха плакати с надпис: „България не е на прасетата“.
Бумърите също не бяхме малко на този площад, превърнат в терен на гражданско недоволство в ΧΧI век, обграден от масивните тежки сгради на един брутален режим, останал в историята.
В Animals огромно прасе лети над фабриката на Battersea Power Station като символ на обсебващата и безотговорна власт, автократизма и алчността. „Летящото прасе стана символ на протест – както пише ΒΒC. – Kато символ намеква за всичко – от антиестаблишмънт протести до оруелска дистопия […]“
Една българска версия на пинкфлойдския Αlgie летя и над площад „Независимост“ с надпис „Ненаситно прасе“.
За българските граждани прасето е разбираем символ. Лакомията на властта явно прозира в бюджета за 2026-та, предизвикал протеста. Неотстъпчивостта, с която мнозинството на ГЕРБ–СДС, ДПС – Ново начало, БСП и „Има такъв народ“ отрязваше всяко разумно предложение и опит за диалог, допълнително нагнети напрежението. Бизнес, синдикати, опозиция, финансови анализатори, а тези дни и Европейската комисия критикуваха проектобюджета, който изземва от бизнеса, преразпределя в полза на репресивен апарат, магистрати и чиновници и захранва с милиарди непрозрачни държавни образувания, като Българската банка за развитие и Българския енергиен холдинг. Накратко: законов обир на средната класа.
Нищо не спря хода на марш на този бюджет: нито безпрецедентната липса на одобрение от Националната комисия за тристранно сътрудничество; нито призивите да се спре главоломното нарастване на публичния дълг; нито фантасмагориите с нереално завишените приходи и счетоводните трикове да се сгъне дефицитът до около 3%.
Още по-малко да се постави началото на реформи – например категориите държавни служители, в това число полицаите, които не плащат осигуровки, да започнат да го правят. За 2025 г. разходите за пенсии са 21,8 млрд. лв., а директният трансфер от държавния бюджет е 11,8 млрд. лв. – по-голям от приходите от осигуровки.
Нито приходите от данък дивидент, предвиден да нарасне двойно – от 5 на 10%, ще компенсират големия дял на сивата икономика (33–34%).
През цялото време управляващите внушаваха, че това е единственият възможен бюджет, че хубавият ще е догодина. И точно когато се навлезе във фазата на окончателно приемане, Бойко Борисов дръпна аварийната спирачка. На сутринта след протеста на 26 ноември той съобщи пред журналисти, че е разпоредил бюджетът да се изтегли.
Събрах подкрепящите партии и „домсъвета“, премиера и финансовия министър като мандатоносител и им казах този бюджет да се изтегли – или да се намери законова форма, защото е приет на първо четене. Докато диалогът не се възстанови… Десетилетия наред съм работил винаги в диалог с Тристранката.
Новината свари неподготвен стълба на управлението Делян Пеевски, който се окопити два часа по-късно, за да контраатакува, че и той можел да блокира парламента със своите симпатизанти. Колко му е. Ще ги качат на автобуси, ще ги докарат пред парламента, ще им дадат плакати в ръцете и ще стоят. Чист криндж.
Даже назначените и протежирани от него в съдебната и изпълнителната власт не биха излезли доброволно в подкрепа на покровителя си.
Не е тайна обаче, че гражданското недоволство плаши Борисов. Само допреди дни той обясняваше как протестите били, за да не се приеме първият бюджет в евро, и нямало нищо лошо да се протестира. След протеста се опита да влезе в кожата на стария Борисов – Генерала, Бате Бойко, познавача на народната социология, който не е „пешка на Пеевски“, както го изкарват от „Да, България“. И дори един човек да протестира, се опитва да чуе какво казва.
От сутрешното изявление на Борисов изминаха повече от 24 часа и освен че „диалогът е възстановен“, съвсем не е ясно какво става с бюджета. На запитване на ClubZ от Министерския съвет са отговорили, че процедурата по приемане е отложена:
Отлагаме бюджетната процедура по приемането на проекта на Закон за държавния бюджет за 2026 г. и бюджетите на ДОО и НЗОК до провеждане на диалог със социалните партньори (синдикати и работодатели). Целта е постигане на съгласие по основните параметри на бюджета.
Не е ясно кои са параметрите. Едва ли обаче ще се намалят разходите за увеличените възнаграждения на полицаите, чиновниците, магистратите. БСП се осмели да заплаши с оттегляне от коалицията, ако бъдат пипнати социалните политики – това била червената им линия:
Компромиси с доходите, семействата, пенсиите, здравето, състоянието на общините не може да има. Ако няма възможност да изпълним тези ангажименти и да продължим заложените социални политики, БСП – Обединена левица ще преосмисли своето участие в управлението.
Впрочем в бюджета за 2026 г. са предвидени 920 млн. евро, с които да се разплащат започнати вече проекти на общините – двойно повече от заложените тази година. Тези средства се управляват от МРРБ, оглавявано от кадъра на БСП Иван Иванов. А вчера вицепремиерът и лидер на БСП Атанас Зафиров бе заснет на влизане в най-големия кабинет в сградата на парламента – 222, някога ползван от бившия Първи – Тодор Живков, а днес обитаван от Пеевски.
Източник: Елисавета Белобрадова / Facebook
Червената линия може да му е начертана там. Председателят на ДПС – Ново начало също гарантира, че всички социални политики ще бъдат запазени.
На този фон дългото затишие откъм ИТН прави впечатление. Поведението им е обяснимо – нямат интерес да бъдат видими в конфликт, който не контролират, и затова просто гласуват заедно с останалите от коалицията. А и министърът на културата от тяхната квота Мариан Бачев бе замесен в гей скандал.
Разбира се, маньовърът на Борисов може да е най-обикновен трик за сваляне на напрежението и за разреждането му в близките седмици – става студено, идват коледните празници… Ако управляващите се откажат от вдигане на осигуровките или от увеличения данък дивидент, могат да спечелят благоразположението на бизнеса и да си стиснат ръцете. После в парламента ще използват аргумента, че вече са постигнали съгласие, и така ще парират възраженията на опозицията.
Малко вероятно е Министерството на финансите да успее да прекрои бюджета така, че да е реформаторски, с дългосрочни политики и устойчиви публични финанси. Независимо че Борисов допусна влизането в еврозоната да е с със стария бюджет – законът изисква да се харчи 1/12 от него месечно и да се спазва правилото, че разходите са само на база събраните приходи от различни източници.
Слабостите на тази власт ясно проличават – липса на стратегическа визия, свръхзависимост от силовото Ново начало в коалицията, а към тях вече се прибавя и страхът от уличното недоволство.
В този смисъл номерът на Борисов може да се окаже не жест на „диалогичност“, а първа стъпка към безопасно отстъпление – да излезе от коалицията като „разумния“, за да отиде на избори в по-добра форма, отколкото ще бъде след няколко месеца. Протестът на 26 ноември недвусмислено му показа, че е излязъл извън границите на политическите кръгове, а той умее да разчита тези знаци.
Гражданите излязоха не само срещу бюджета за 2026 г., а срещу опитите да бъдат третирани като статисти в собствената си държава – без право на глас, без участие в решенията и без гаранция, че утре правилата няма да се променят пак, пак и пак, стига Пеевски да разпореди.
Така че въпросът не е дали властта може да падне, а как ще изглежда самото падане.
България няма да е на прасетата.