One of the things that makes Cloudflare unique is our Innovation Weeks. Rather than having one large conference annually, we have multiple Innovation Weeks throughout the year to highlight new product announcements, beta products opening up to general availability, and share how our customers are using Cloudflare to help build a better Internet.
Internally, these weeks generate a lot of energy and excitement as well, as they provide an opportunity for teams from across Cloudflare to work together on product delivery and celebrate company-wide successes. In 2021, we had seven Cloudflare Innovation Weeks. As we start planning our 2022 Innovation Weeks, we are reflecting back on the highlights from each of these weeks.
Security Week kicked off Cloudflare’s 2021 Innovation Weeks with a series of foundational security announcements. The Internet wasn’t built with security in mind, but the products and partnerships announced this week continued Cloudflare’s core mission of helping build a better Internet—one that companies of all sizes can plug into and be protected by default from the types of attacks that have historically resulted in loss of data, computing resources, and customer confidence.
During our first Impact Week, we reflected on how we are achieving Cloudflare’s mission–helping build a better Internet– and why we continue to prioritize projects that give back to the Internet. Impact Week highlighted some of the things we are doing as a company around environmental, social and governance initiatives. We launched Project Pangea, a free program to provide secure, reliable access to the Internet for community networks that support under-served communities. We also shared how we are committed to helping build a green Internet through efficiency, renewable energy, and providing developers a choice to run their workloads in the most energy efficient data centers. In addition, we published our first human rights policy in order to better serve our mission and core values.
We launched two amazing performance features with Signed Exchanges reducing load times and increasing SEO rankings with one click as well as Early Hints which can reduce loading times by 30%.
As part of Speed week, we also announced Cloudflare Images which stores, resizes, optimizes and serves images so that all of our customers can build a scalable, affordable image pipeline.
This is the week in which we celebrate Cloudflare’s birthday. We launched the company 11 years ago: September 27, 2010. It has been our tradition, since our first birthday, to use this week to launch innovative products that we think of as our gift back to the Internet. In 2021, we announced Cloudflare R2, our object-based storage with no egress fees, tackled solutions to Email Spoofing and Phishing, shared how we are expanding our network into office buildings as well as many more product announcements and Cloudflare TV executive fireside chats and product discussions.
During Full Stack Week, we brought the vision of the Network is the Computer to life — allowing developers to build their entire application on our network, soup to nuts. Over the course of the week, we made a series of announcements, each providing another critical piece of the puzzle, necessary to build a full stack application.
In July 2021, as part of Impact Innovation Week, we announced our intention to launch Crawler Hints as a means to reduce the environmental impact of web searches. We spent the weeks following the announcement hard at work, and in October 2021, we announced General Availability for the first iteration of the product. This post explains how we built it, some of the interesting engineering problems we had to solve, and shares some metrics on how it’s going so far.
Before We Begin…
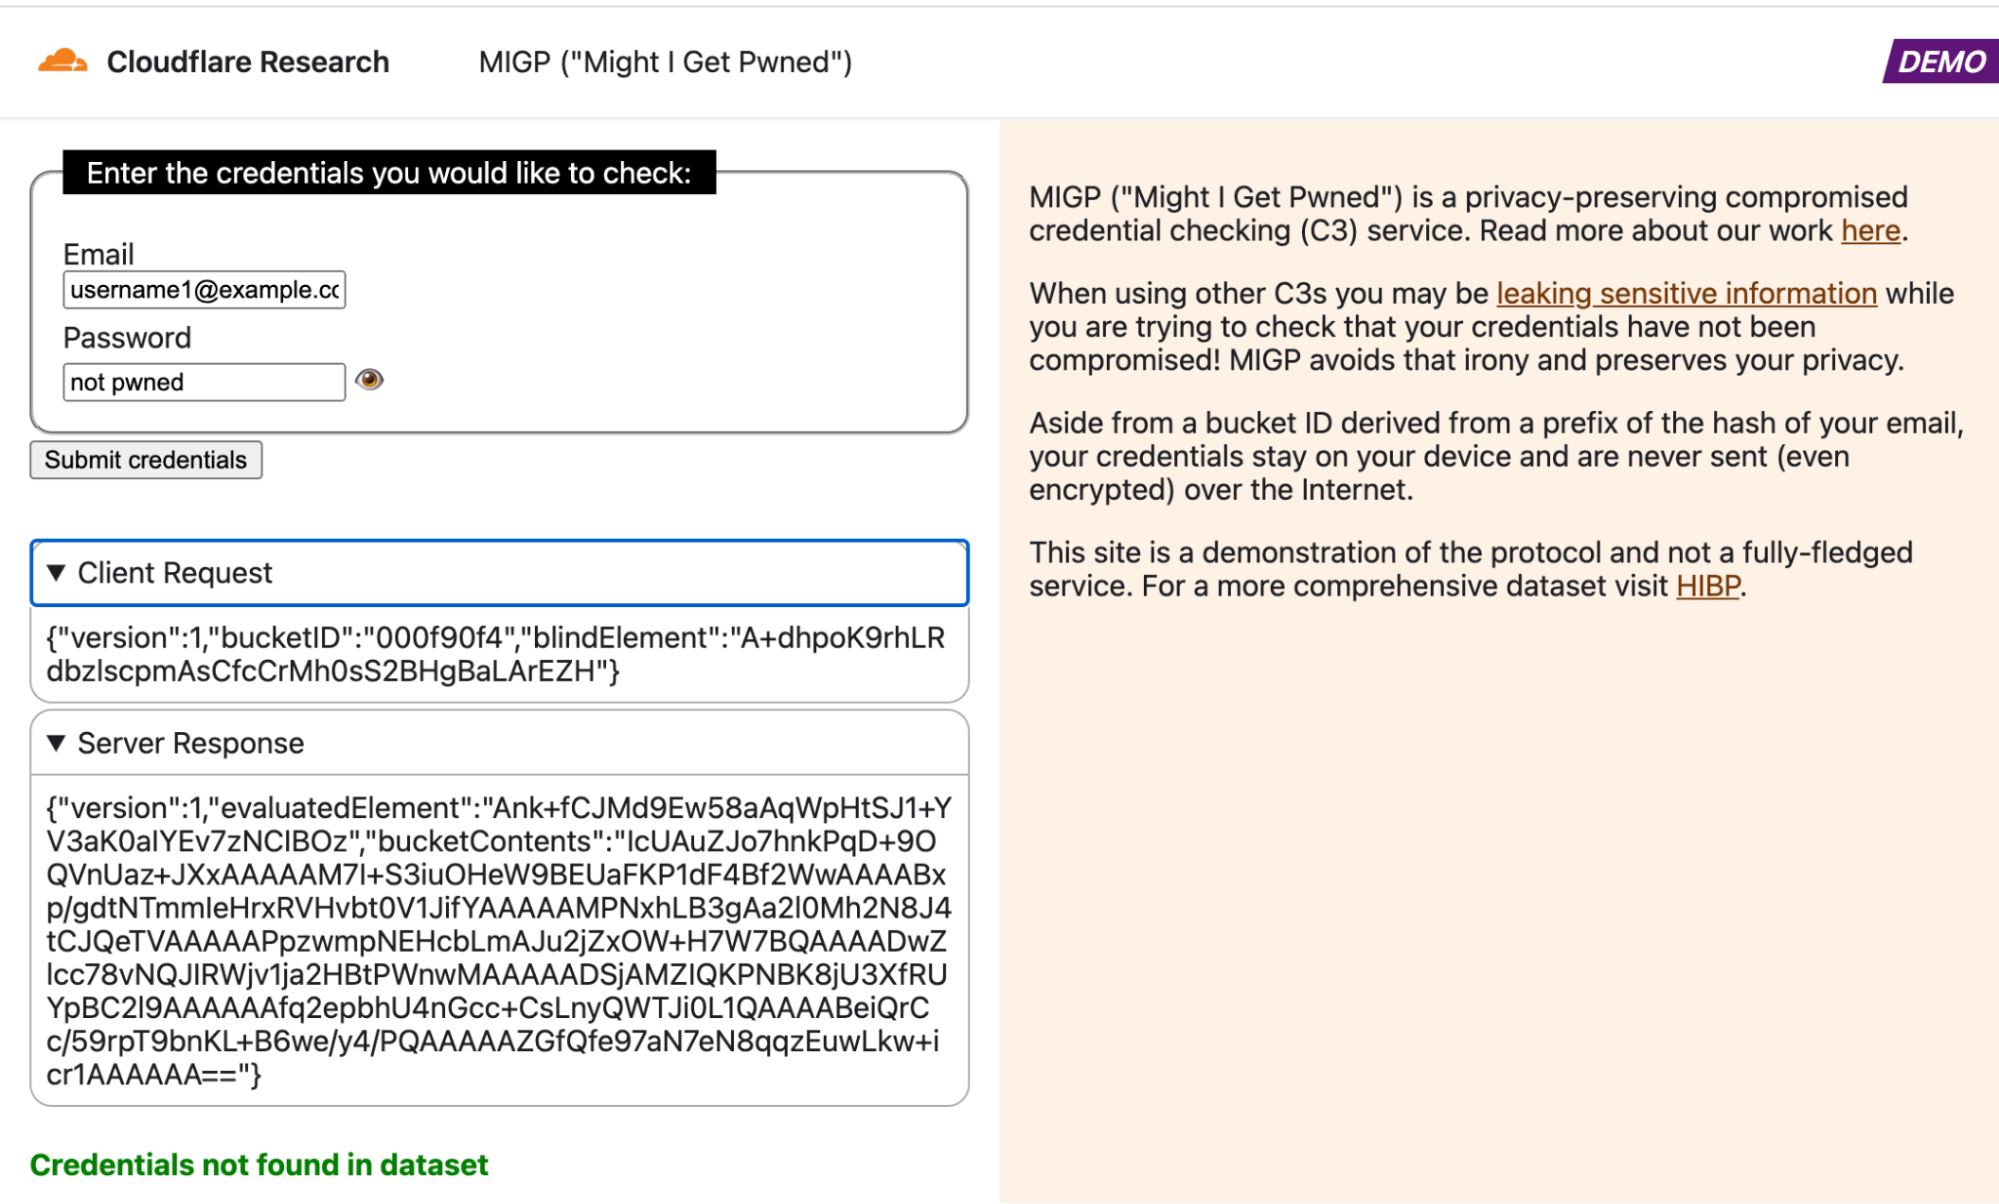
Search indexers crawl sites periodically to check for new content. Algorithms vary by search provider, but are often based on either a regular interval or cadence of past updates, and these crawls are often not aligned with real world content changes. This naive crawling approach may harm customer page rank and also works to the detriment of search engines with respect to their operational costs and environmental impact. To make the Internet greener and more energy efficient, the goal of Crawler Hints is to help search indexers make more informed decisions on when content has changed, saving valuable compute cycles/bandwidth and having a net positive environmental impact.
Cloudflare is in an advantageous position to help inform crawlers of content changes, as we are often the “front line” of the interface between site visitors and the origin server where the content updates take place. This grants us knowledge of some key data points like headers, content hashes, and site purges among others. For customers who have opted in to Crawler Hints, we leverage this data to generate a “content freshness score” using an ensemble of active and passive signals from our customer base and request flow. To help with efficiency, Crawler Hints helps to improve SEO for websites behind Cloudflare, improves relevance for search engine users, and improves origin responsiveness by reducing bot traffic to our customers’ origin servers.
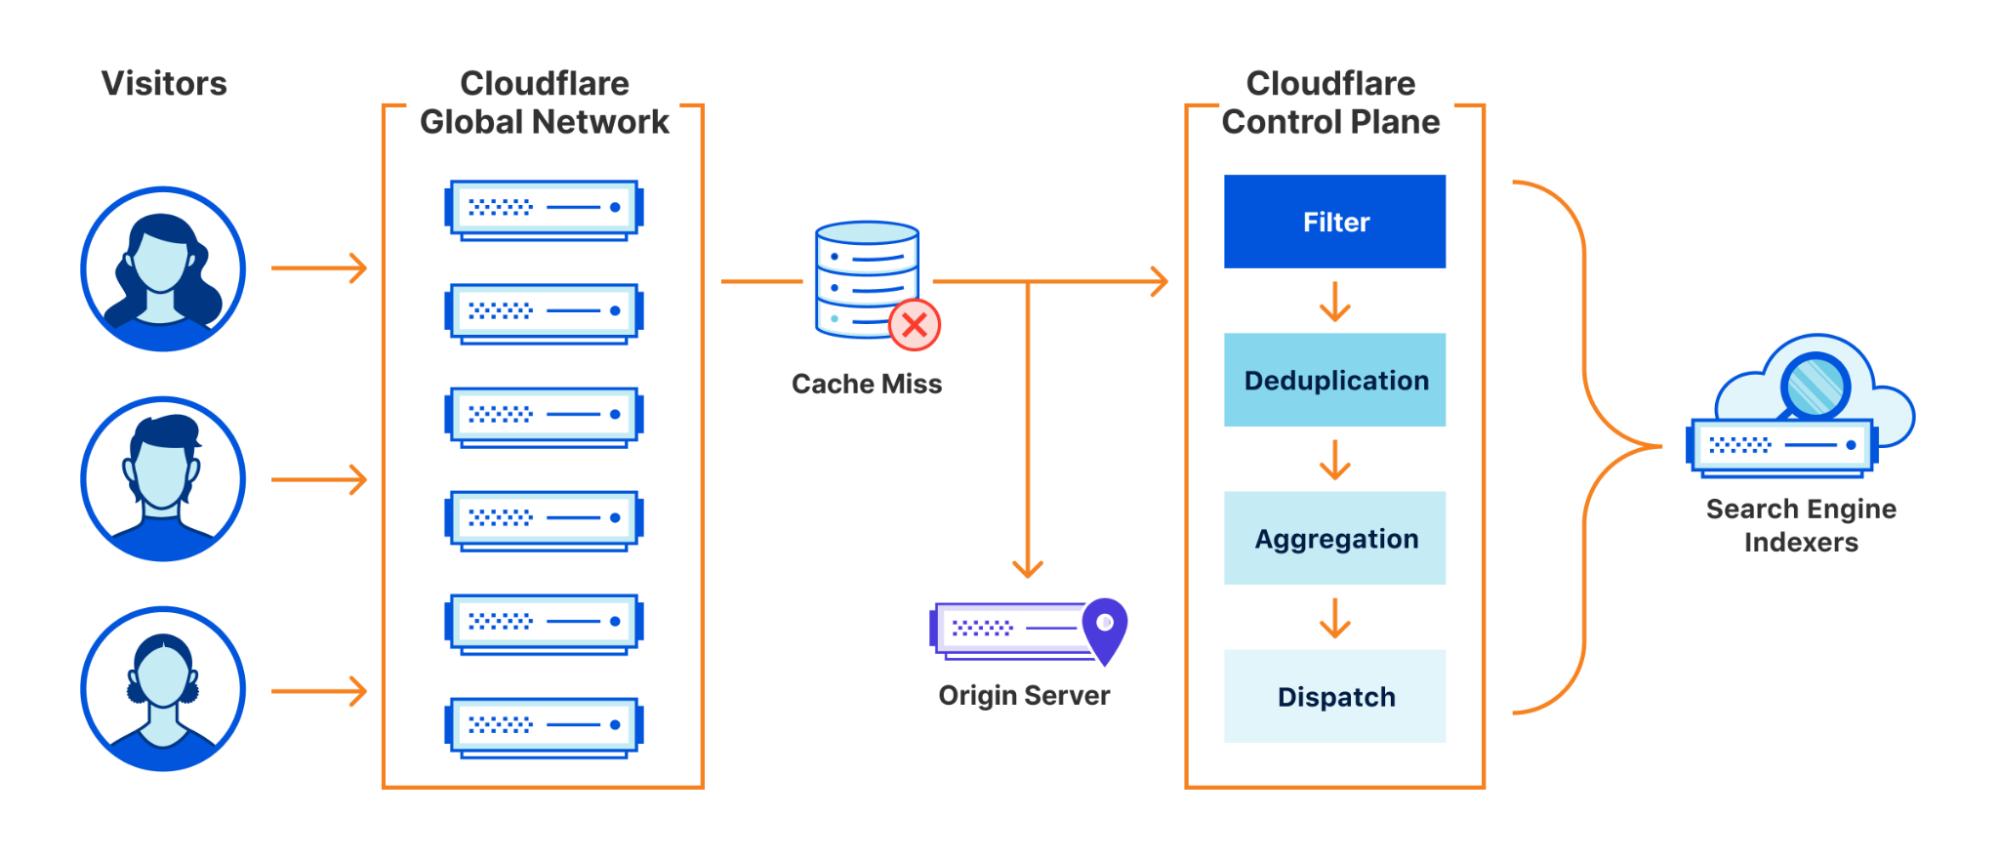
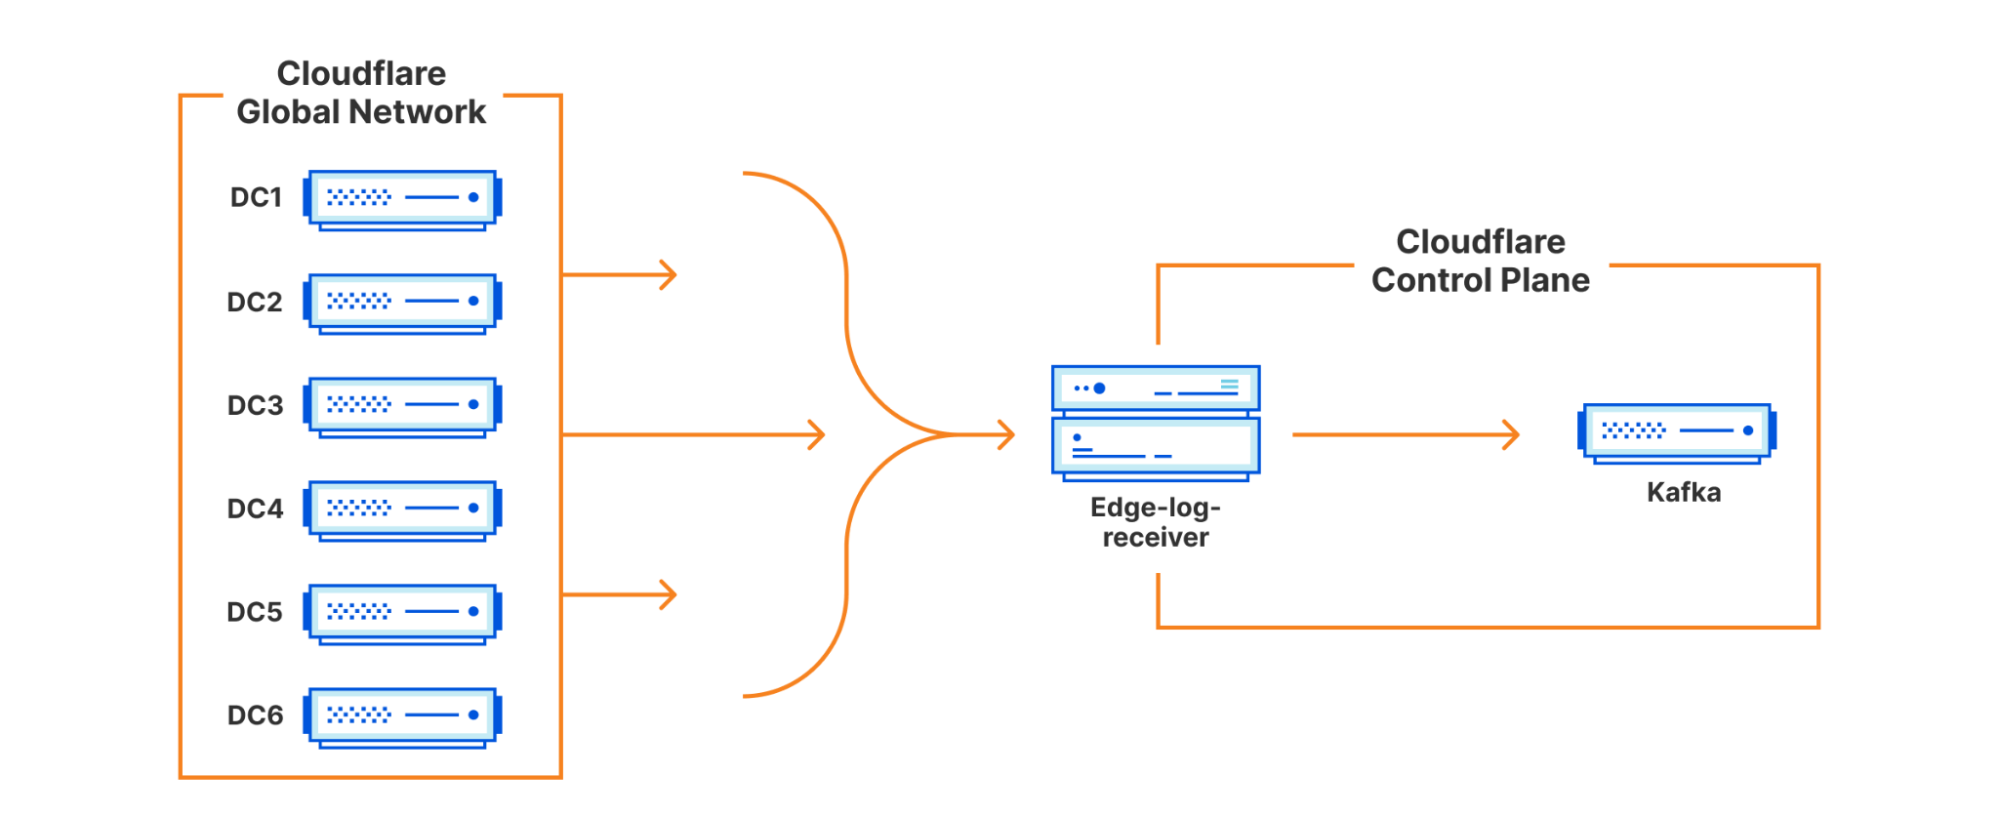
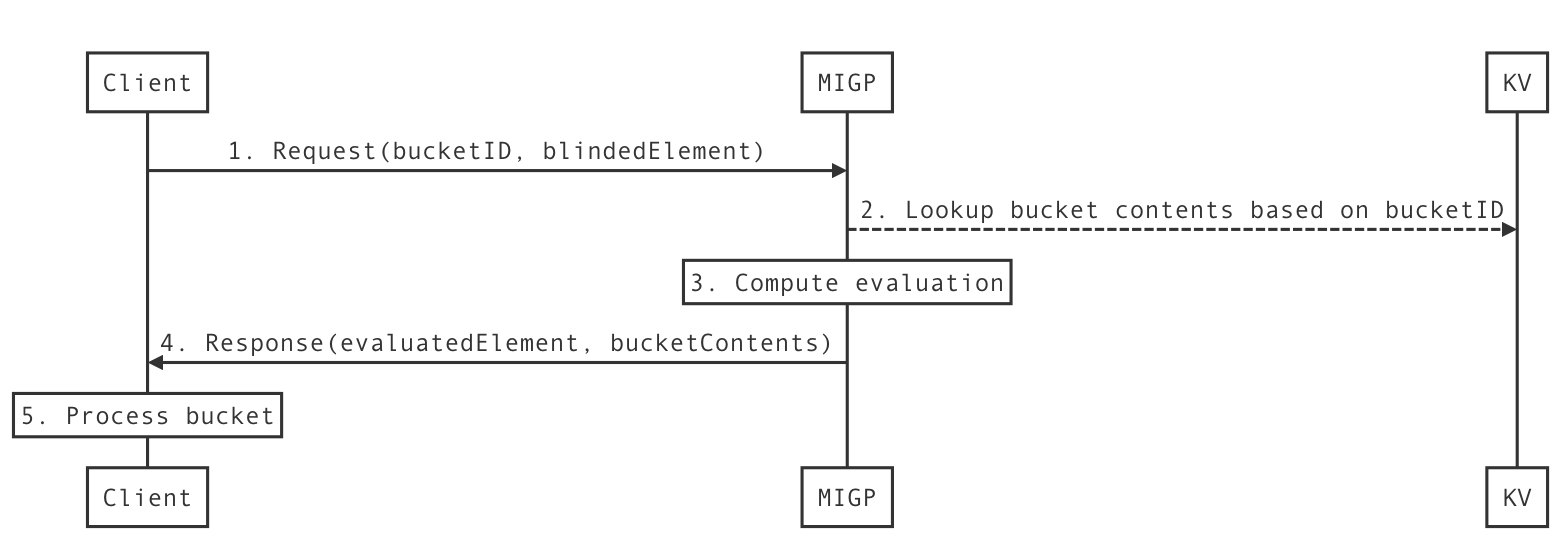
A high level design of the system we built looks as follows:
In this blog we will dig into each aspect of it in more detail.
Keeping Things Fresh
Cloudflare has a large global network spanning 250 cities. A popular use case for Cloudflare is to use our CDN product to cache your website’s assets so that users accessing your site can benefit from lightning fast response times. You can read more about how Cloudflare manages our cache here. The important thing to call out for the purpose of this post is that the cache is Data Center local. A cache hit in London might be a cache miss in San Francisco unless you have opted-in to tiered-caching, but that is beyond the scope of this post.
For Crawler Hints to work, we make use of a number of signals available at request time to make an informed decision on the “freshness” of content. For our first iteration of Crawler Hints, we used a cache miss from Cloudflare’s cache as a starting basis. Although a naive signal on its own, getting the data pipelines in place to forward cache miss data from our global network to our control plane meant we would have everything in place to iterate on and improve the signal processing quickly going forward. To do this, we leveraged some existing services from our data team that takes request data , marshalls it into Cap’n Proto format, and forwards it to a message bus (we use apache Kafka). These messages include the URLs of the resources that have met the signal criteria, along with some additional metadata for analytics/future improvement.
The amount of traffic our global network receives is substantial. We serve over 28 million HTTP requests per second on average, with more than 35 million HTTP requests per second at peak. Typically, Cloudflare teams sample this data to enable products such as being alerted when you are under attack. For Crawler Hints, every cache miss is important. Therefore, 100% of all cache misses for opted-in sites were sent for further processing, and we’ll discuss more on opt-in later.
Redis as a Distributed Buffer
With messages buffered in Kafka, we can now begin the work of aggregation and deduplication. We wrote a consumer service that we call an ingestor. The ingestor reads the data from Kafka. The ingestor performs validation to ensure proper sanitization and data integrity and passes this data onto the next stage of the system. We run the ingestor as part of a Kafka consumer group, allowing us to scale our consumer count up to the partition size as throughput increases.
We ultimately want to deliver a set of “fresh” content to our search partners on a dynamic interval. For example, we might want to send a batch of 10,000 URLs every two minutes. There are, however, a couple of important things to call out though:
There should be no duplicate resources in each batch.
We should strike a balance in our size and frequency such that overall request size isn’t too large, but big enough to remove some pressure on the receiving API by not sending too many requests at once.
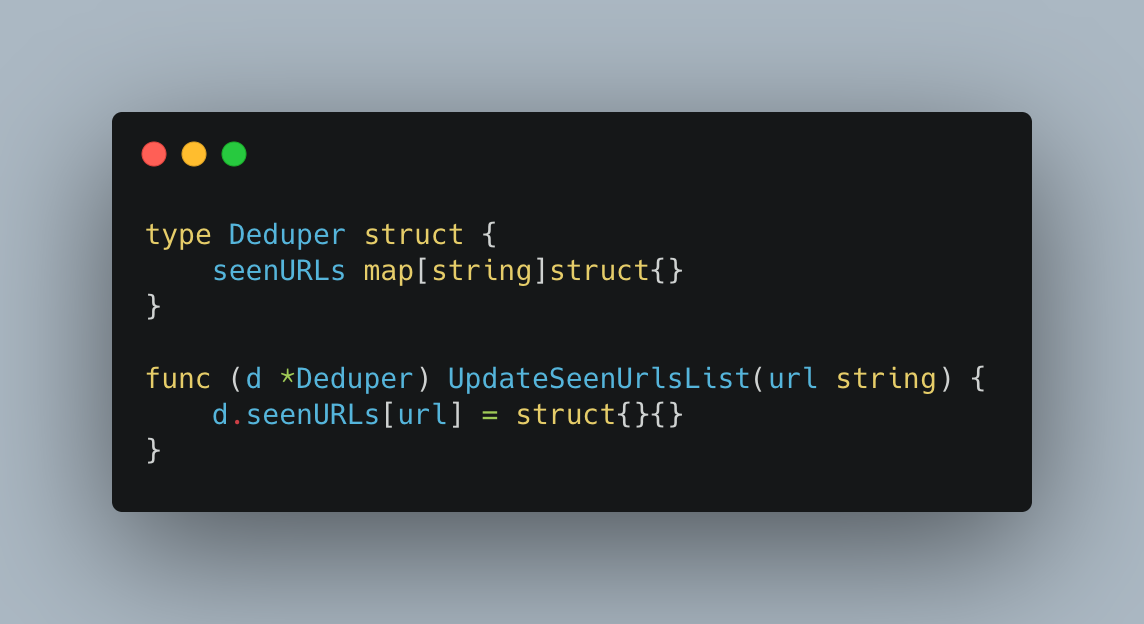
For the deduplication, the simplest thing to do would be to have an in-memory map in our service to track resources between a pre-specified interval. A naive implementation in Go might look something like this.
The problem with this approach is we have little resilience. If the service was to crash, we would lose all the data for our current batch. Furthermore, if we were to run multiple instances of our services, they would all have a different “view” of which resources they had seen before and therefore we would not be deduplicating.To mitigate this issue, we decided to use a specialist caching service. There are a number of distributed caches that would fit the bill, but we chose Redis given our team’s familiarity with operating it at scale.
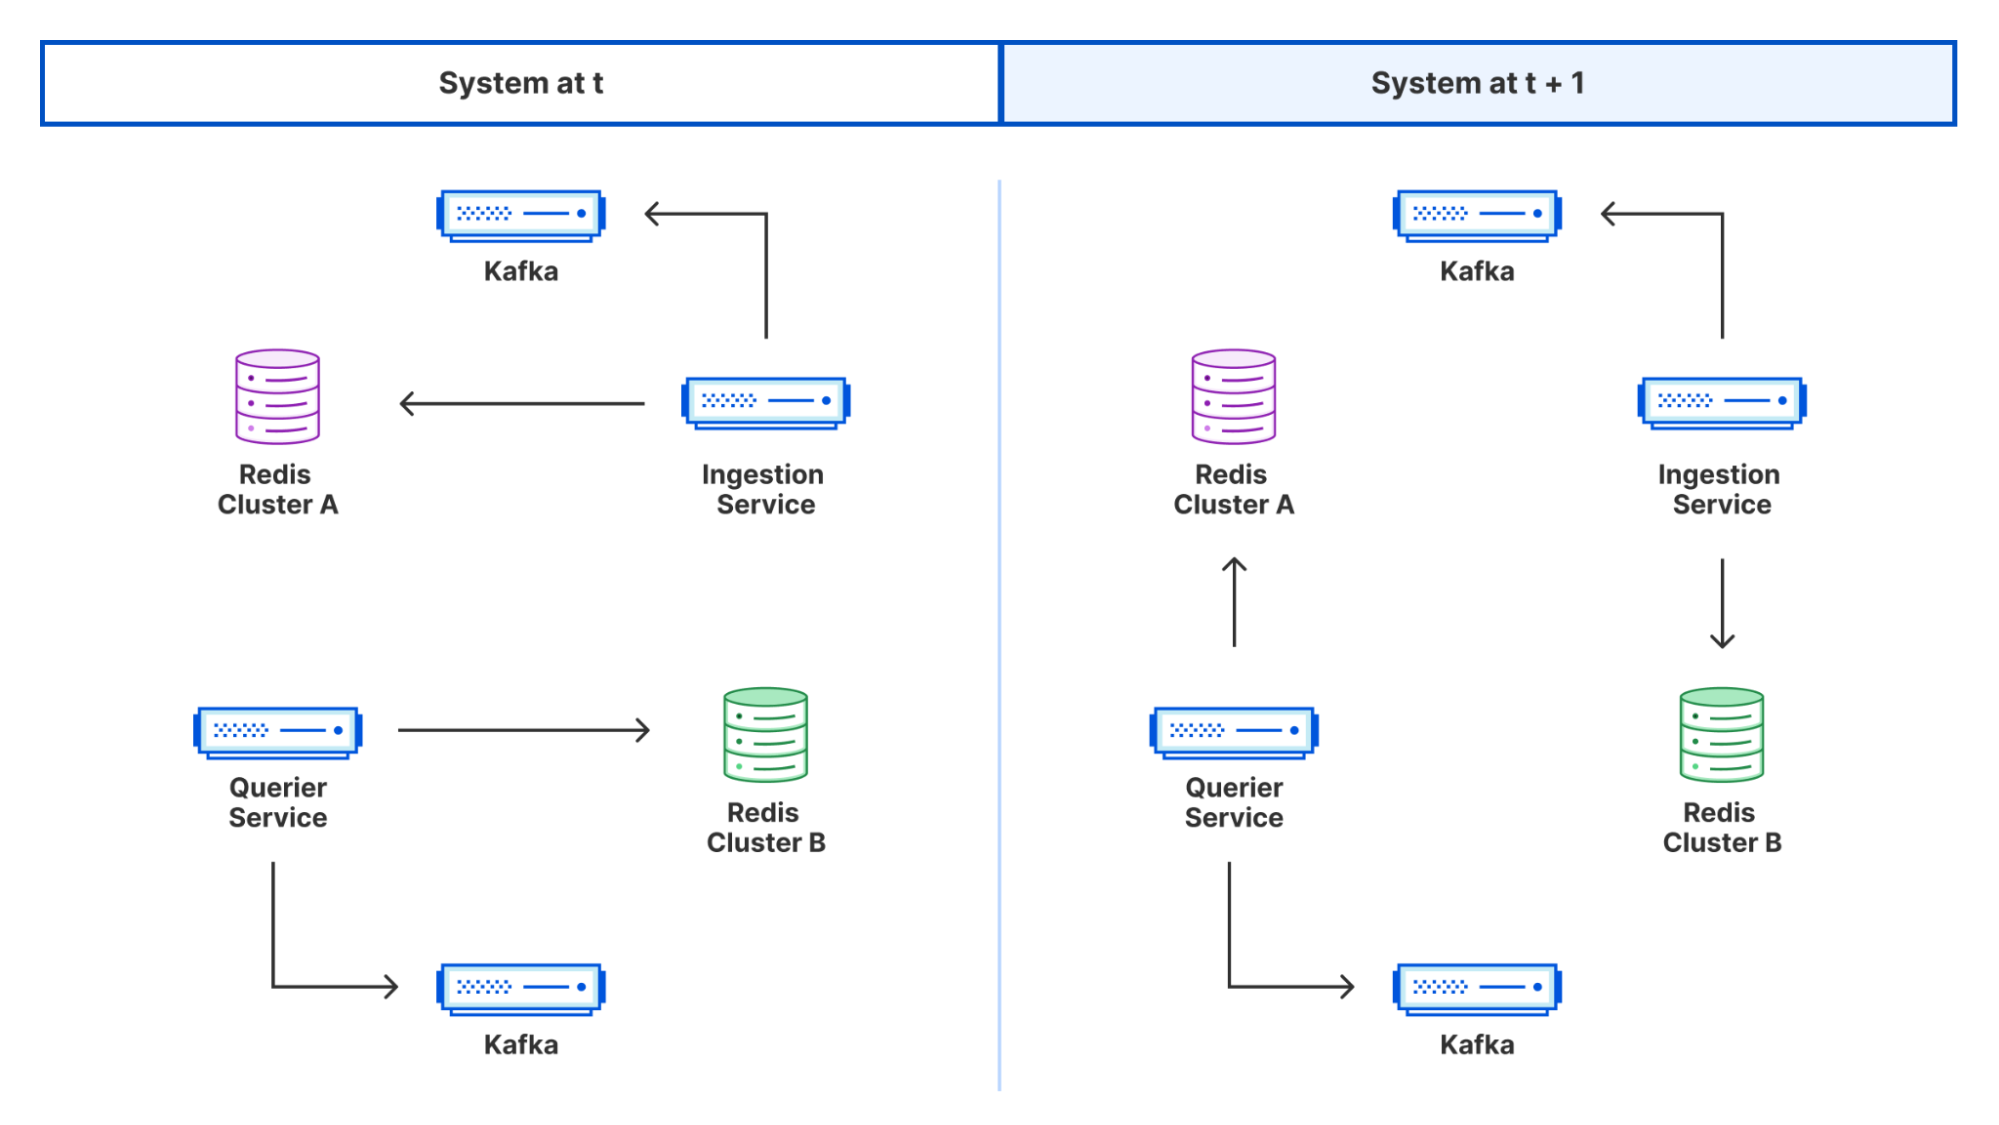
Redis is well known as a Key Value(KV) store often used for caching things,optionally with a specified Time To Live(TTL). Perhaps slightly less obvious is its value as a distributed buffer, housing ephemeral data with periodic flush/tear-downs. For Crawler Hints, we leveraged both these traits via a multi-generational, multi-cluster setup to achieve a highly available rolling aggregation service.
Two standalone Redis clusters were spun up. For each generation of request data, one cluster would be designated as the active primary. The validated records would be inserted as keys on the primary, serving the dual purpose of buffering while also deduplicating since Redis keys are unique. Separately, a downstream service (more on this later!) would periodically issue the command for these inserters to switch from the active primary (cluster A) to the inactive cluster (cluster B). Cluster A could then be flushed with records being batch read in a size of our choosing.
Buffering for Dispatch
At this point, we have clean, batched data. Things are looking good! However, there’s one small hiccup in the plan: we’re reading these batches from Redis at some set interval. What if it takes longer to dispatch than the interval itself? What if the search partner API is having issues?
We need a way to ensure the durability of the batch URLs and reduce the impact of any dispatch issues. To do this, we revisit an old friend from earlier: Kafka. The batches that get read from Redis are then fed into a Kafka topic. We wrote a Kafka consumer that we call the “dispatcher service” which runs within a consumer group to enable us to scale it if necessary just like the ingestor. The dispatcher reads from the Kafka topic and sends a batch of resources to each of our API partners.
Launching in tandem with Cloudflare, Crawler Hints was a joint venture between a few early adopters in the search engine space to provide a means for sites to inform indexers of content changes called IndexNow. You can read more about this launch here. IndexNow is a large part of what makes Crawler Hints possible. As part of its manifest, it provides a common API spec to publish resources that should be re-indexed. The standardized API makes abstracting the communication layer quite simple for the partners that support it. “Pushing” these signals to our search engine partners is a big step away from the inefficient “Pull” based model that is used today (you can read more about that here). We launched with Yandex and Bing as Search Engine Partners.
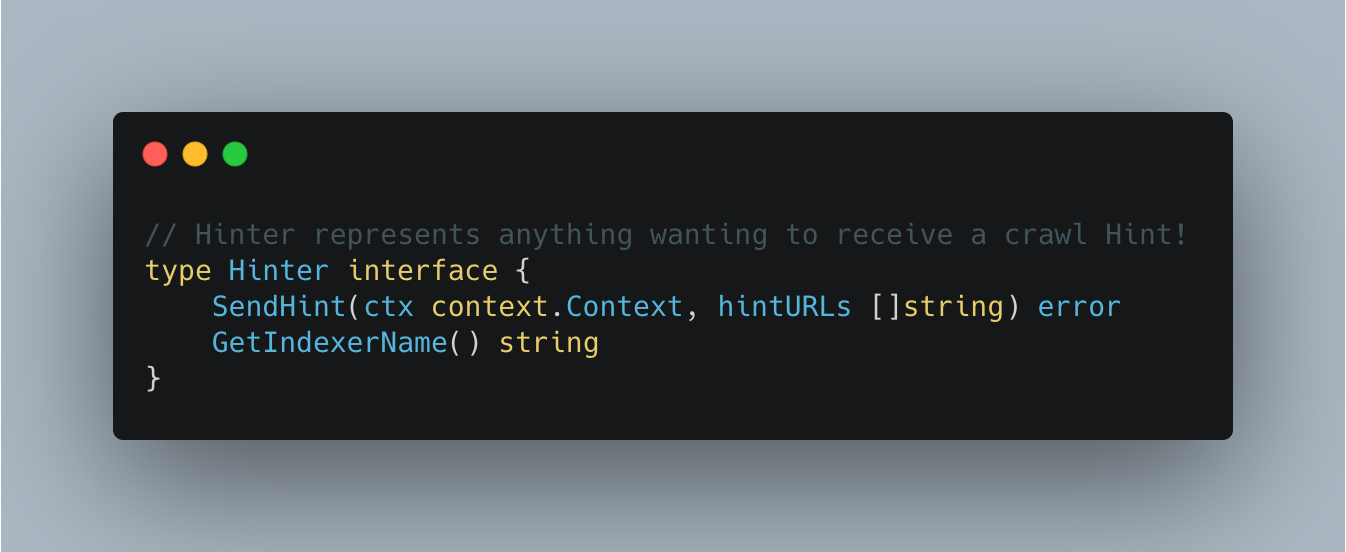
To ensure we can add more partners in the future, we defined an interface which we call a “Hinter”.
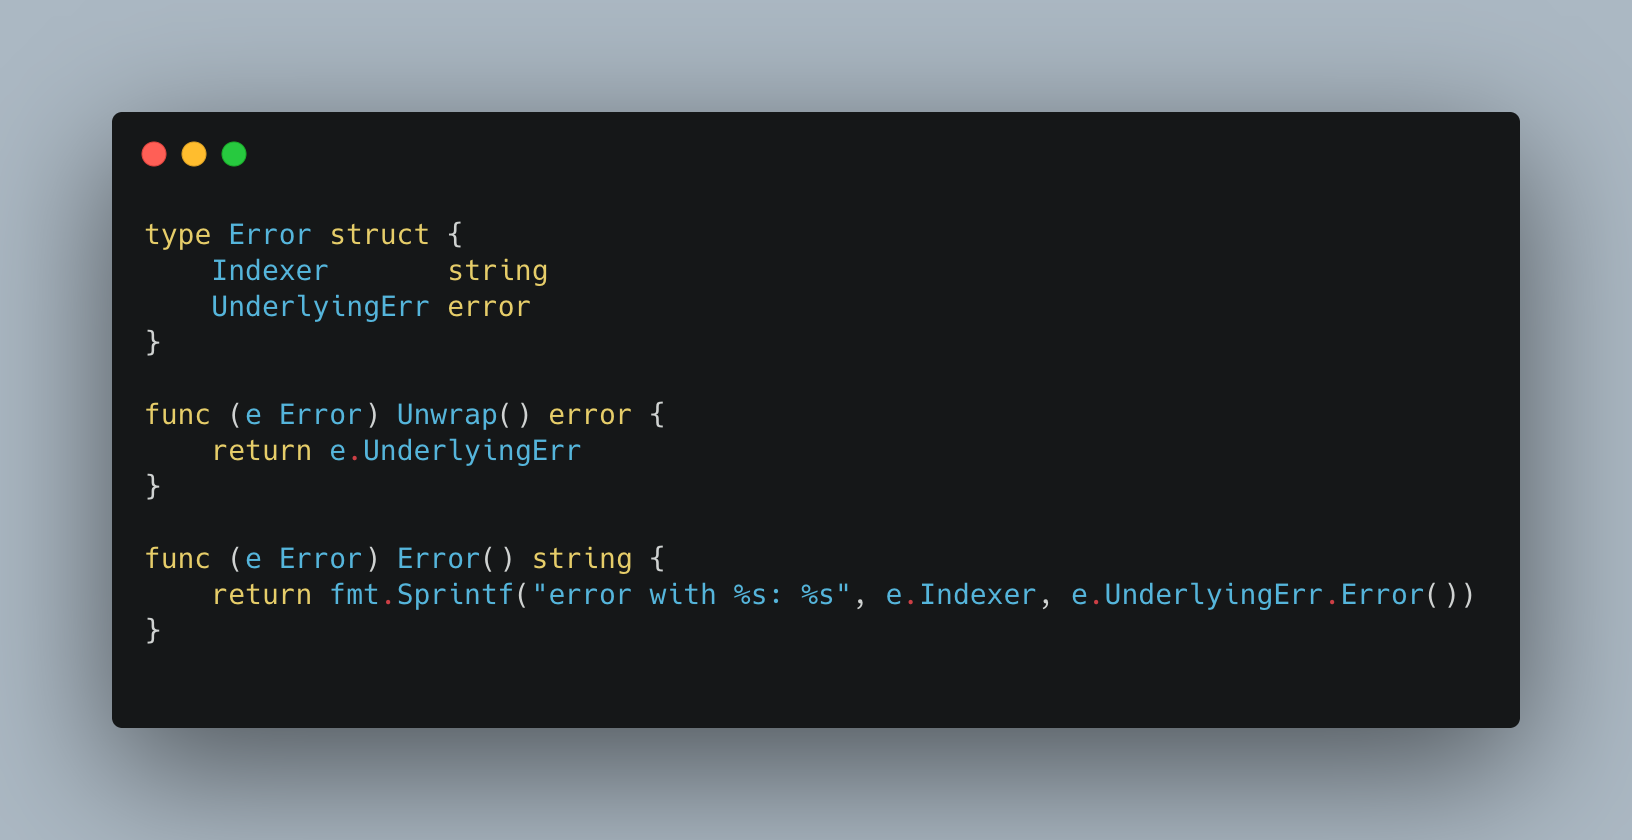
We then satisfy this interface for each partner that we work with. We return a custom error from the Hinter service that is of type *indexers.Error. The definition of which is:
This allows us to “bubble up” information about which indexer has failed and increment metrics and retry only those calls to indexers which have failed.
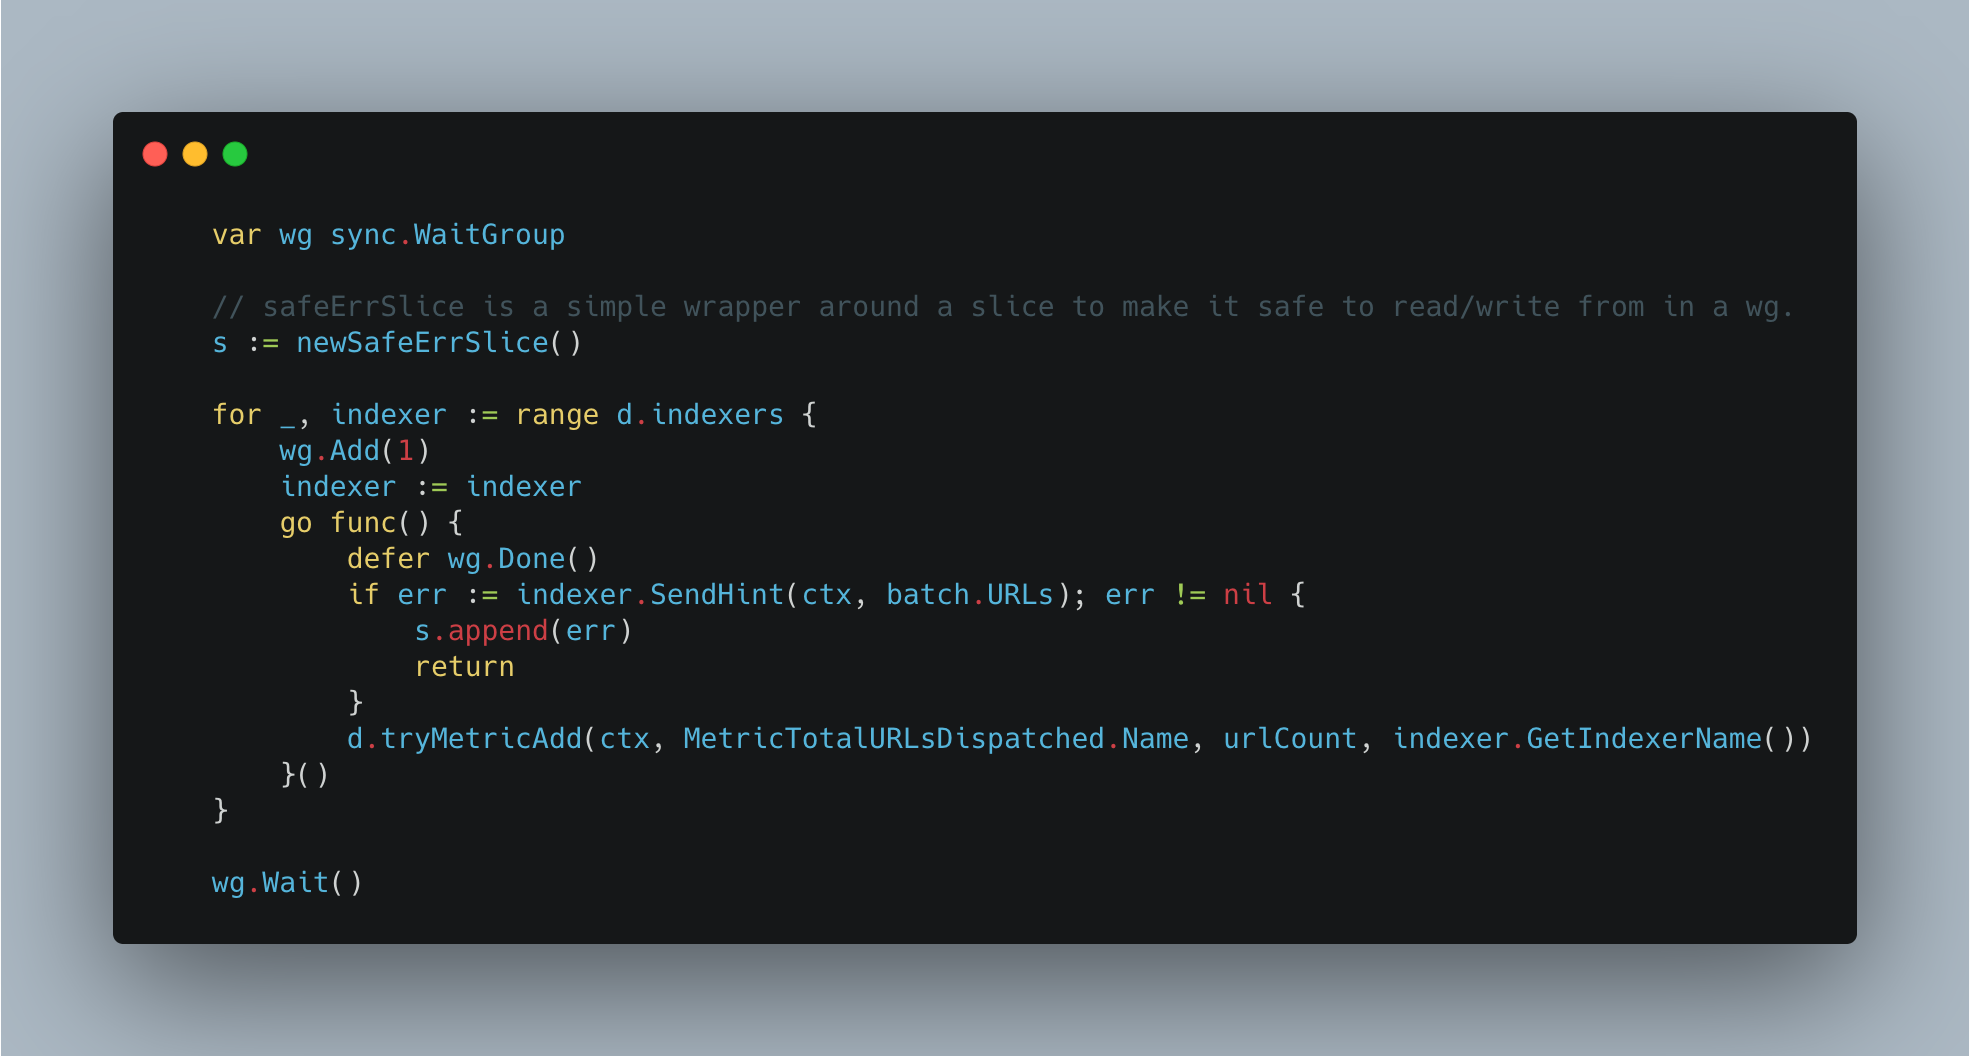
This all culminates together with the following in our service layer:
Simple, performant, maintainable, AND easy to add more partners in the future.
Rolling out Crawler Hints
At Cloudflare, we often release things that haven’t been done before at scale. This project is a great example of that. Trying to gauge how many users would be interested in this product and what the uptake might be like on day one, day ten, and day one thousand is close to impossible. As engineers responsible for running this system, it is essential we build in checks and balances so that the system does not become overwhelmed and responds appropriately. For this particular project, there are three different types of “protection” we put in place. These are:
Customer opt-in
Monitoring & Alerts
System resilience via “self-healing”
Customer opt-in
Cloudflare takes any changes that can impact customer traffic flow seriously. Considering Crawler Hints has the potential to change how sites are seen externally (even if in this instance the site’s viewers are robots!) and can impact things like SEO and bandwidth usage, asking customers to opt-in is a sensible default. By asking customers to opt-in to the service, we can start to get an understanding of our system’s capacity and look for bottle necks and how to remove them. To do this, we make extensive use of Prometheus, Grafana, and Kibana.
Monitoring & Alerting
We do our best to make our systems as “self-healing” and easy to run as possible, but as they say, “By failing to prepare, you are preparing to fail.” We therefore invest a lot of time creating ways to track the health and performance of our system and creating automated alerts when things fall outside of expected bounds.
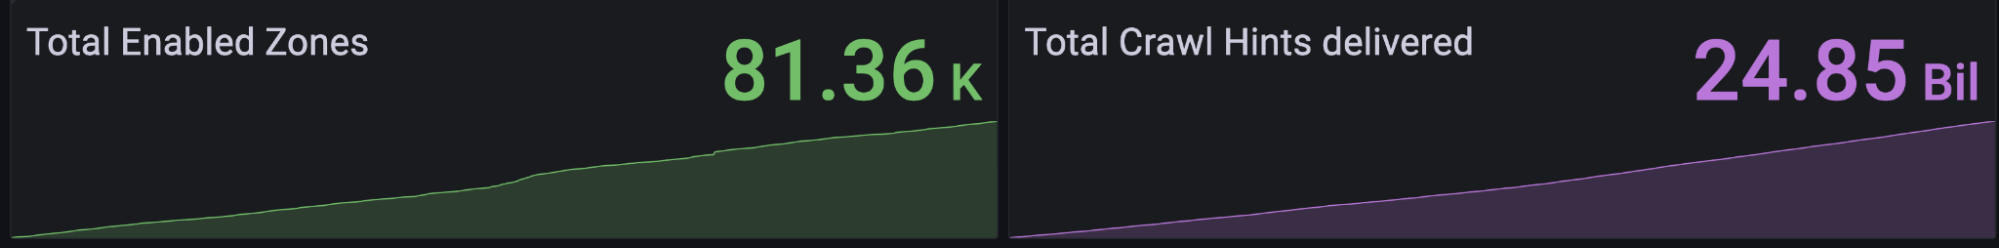
Below is a small sample of the Grafana dashboard we created for this project. As you can see, we can track customer enablement and the rate of hint dispatch in real time. The bottom two panels show the throughput of our Kafka clusters by partition. Even just these four metrics give us a lot of insight into how things are going, but we also track (as well as other things):
Lag on Kafka by partition (how far behind real time we are)
Bad messages received from Kafka
Amount of URLs processed per “run”
Response code per index partner over time
Response time of partner API over time
Health of the Redis clusters (how much memory is used, frequency of commands we are using received by the cluster)
Memory, CPU usage, and pods available against configured limits/requests
It seems a lot to track, but this information is invaluable to us, and we use it to generate alerts that notify the on-call engineer if a threshold is breached. For example, we have an alert that would escalate to an engineer if our Redis cluster approached 80% capacity. For some thresholds we specify, we may want the system to “self-heal.” In this instance, we would want an engineer to investigate as this is outside the bounds of “normal,” and it might be that something is not working as expected. An alternative reason that we might receive alerts is that our product has increased in popularity beyond our expectations, and we simply need to increase the memory limit. This requires context and is therefore best left to a human to make this decision.
System Resilience via “self-healing”
We do everything we can to not disturb on-call engineers, and therefore, we try to make the system as “self-healing” as possible. We also don’t want to have too much extra resource running as it can be expensive and use limited capacity that another Cloudflare service might need more – it’s a trade off. To do this, we make use of a few patterns and tools common in every distributed engineer’s toolbelt. Firstly, we deploy on Kubernetes. This enables us to make use of great features like Horizontal Pod Autoscaling. When any of our pods reach ~80% memory usage, a new pod is created which will pick up some of the slack up to a predefined limit.
Secondly, by using a message bus, we get a lot of control over the amount of “work” our services have to do in a given time frame. In general, a message bus is “pull” based. If we want more work, we ask for it. If we want less work, we pull less. This holds for the most part, but with a system where being close to real time is important, it is essential that we monitor the “lag” of the topic, or how far we are behind real time. If we are too far behind, we may want to introduce more partitions or consumers.
Finally, networks fail. We therefore add retry policies to all HTTP calls we make before reporting them a failure. For example, if we were to receive a 500 (Internal Server Error) from one of our partner APIs, we would retry up to five times using an exponential backoff strategy before reporting a failure.
Data from the first couple of months
Since the release of Crawler Hints on October 18, 2021 until December 15, 2021, Crawler Hints has processed over twenty five billion crawl signals, has been opted-in to by more than 81,000 customers, and has handled roughly 18,000 requests per second. It’s been an exciting project to be a part of, and we are just getting started.
What’s Next?
We will continue to work with our partners to improve the standard even further and continue to improve the signaling on our side to ensure the most valuable information is being pushed on behalf of our customers in a timely manner.
If you’re interested in building scalable services and solving interesting technical problems, we are hiring engineers on our team in Austin, Lisbon, and London.
The Internet is a dynamic place. Websites are constantly changing as technologies and business practices evolve. What was front-page news is quickly moved into a sub-directory. To ensure website visitors continue to see the correct webpage even if it has been moved, administrators often implement URL redirects.
A URL redirect is a mapping from one location on the Internet to another, effectively telling the visitor’s browser that the location of the page has changed, and where they can now find it. This is achieved by providing a virtual ‘link’ between the content’s original and new location.
URL Redirects have typically been implemented as Page Rules within Cloudflare, up to a maximum of 125 URL redirects per zone. This limitation meant customers with a need for more URL redirects had to implement alternative solutions such Cloudflare Workers to achieve their goals.
To simplify the management and implementation of URL redirects at scale we have created Bulk Redirects. Bulk Redirects is a new product that allows an administrator to upload and enable hundreds of thousands of URL redirects within minutes, without having to write a single line of code.
We’ve moved!
Mail forwarding is a product offered by postal services such as USPS and Royal Mail that allows you to continue to receive letters and parcels even if they are sent to an address where you no longer reside.
The postal services achieve this by effectively maintaining a register of your new location and your old location. This allows the systems to detect ‘this letter is for Sam Marsh at address A, but he now lives at address B, therefore send the mail there’.
This problem can be solved by manually updating my bank, online shops, etc. and having them send the parcels and letters directly to my new address. However, that assumes I know of every person and business who has my address. And it also relies on those people to remember I moved address and make updates on their side. For example, Grandma Marsh might have forgotten about my new address — I’ve moved a lot — and she may send my birthday card to my old address. Or all those Christmas cards from people who I don’t speak with regularly. Those will go to my old address also. To solve this, I can use mail forwarding to ensure I still receive my cards and other mail, even though I no longer live at that address.
URL redirects are the Internet equivalent of mail forwarding.
With this technology, our sales and marketing teams can use the vanity URL all across the Internet, safe in the knowledge that should the backend systems change they won’t need to go to all the places this URL has been posted and update it. Instead, the intermediary system that handles the URL redirects can be updated. One location. Not thousands.
Why use URL redirects?
URL redirects are used to solve a number of use cases. One such common use case is to use URL redirects to force all visitors to connect to the website over a secure HTTPS connection, instead of via plain HTTP, to improve security. It’s such a common use case we created a toggle in the Cloudflare dashboard, “Always use HTTPS”, which redirects all HTTP requests to HTTPS when enabled.
URL redirects are also used for vanity domains and hyperlinks. In these scenarios, URL redirects are deployed to provide a mapping of short, user-friendly URLs to long, server-friendly URLs. Not only are shorter URLs more memorable, but they are better scoring from an SEO perspective. According to Backlinko, ‘Excessively long URLs may hurt a page’s search engine visibility. In fact, several industry studies have found that short URLs tend to have a slight edge in Google’s search results.’.
Another use case is where a company may have a local domain for each of their markets, which they want to redirect back to the main website, e.g., redirect www.example.fr and www.example.de to www.example.com/eu/fr and www.example.com/eu/de, respectively.
This also covers company acquisition, where a company is acquired and the acquiring company wants to redirect hyperlinks to the relevant pages on their own website, e.g., redirect www.example.com to www.companyB.com/portfolio/example.
Finally, one of the most common use cases for URL redirects is to maintain uptime during a website migration. As companies migrate their websites from one platform to another, or one domain to another, URL redirects ensure visitors continue to see the correct content. Without these URL redirects, hyperlinks in emails, blogs, marketing brochures, etc. would fail to load, potentially costing the business revenue in lost sales and brand damage. For example, www.example.com/products/golf/product-goes-here would redirect to the new website at products.example.com/golf/product-goes-here.
How are URL redirects implemented today?
Ensuring these URL redirects are executed correctly is often the job of the reverse proxy — a server which sits between the client and the origin whose job is, amongst many others, to re-route received traffic to the correct destination.
For example, when using NGINX, a popular web server, the administrator would have a line in the config similar to the one below to implement a URL redirect:
Historically, these web servers were located physically within a company’s data center. Administrators then had full control over the URLs received, and could create the redirect rules as and when needed.
As the world rapidly migrates on-premise applications and solutions to the cloud, administrators can find themselves in a situation where they can no longer do what they previously could. Not being responsible for the origin has a number of benefits, but it also comes with drawbacks such as lack of ‘control’. Previously, an administrator could quickly add a few config lines to the web server in front of their ecommerce platform. Moving to an online hosted platform makes this much more difficult to do.
As such, administrators have moved to platforms like Cloudflare where functionality such as URL redirects can be implemented in the cloud without the need to have administrator access to the origin.
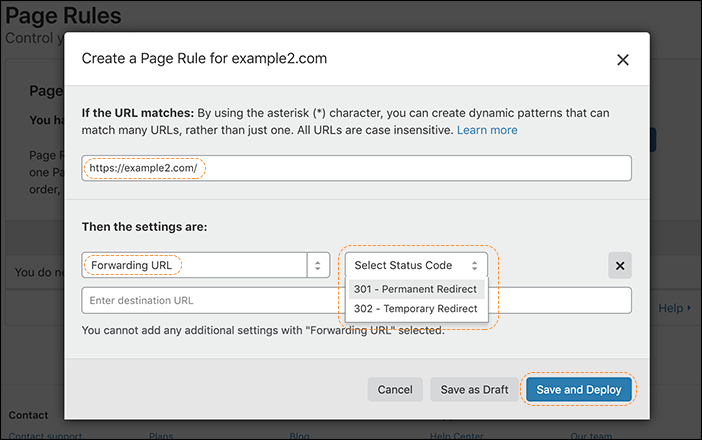
The first way to implement a URL Redirect in Cloudflare is via a Forwarding URLPage Rule. Users can create a Page Rule which matches on a specific URL and redirects matching traffic to another specific URL, along with a status code — either a permanent redirect (301) or a temporary redirect (302):
Another method is to use Cloudflare Workers to implement URL redirects, either individually or as a map. For example, the code below is used to create a URL redirect map which runs when the Worker is invoked:
This snippet is taken from the Cloudflare Workers examples library and can be used to scale beyond the 125 URL redirect limit of Page Rules. However, it does require the administrator to be comfortable working with code and correctly configuring their Cloudflare Workers.
Introducing: Bulk Redirects
Speaking with Cloudflare users about URL redirects and their experience with our product offerings, “Give me a product which lets me upload thousands of URL redirects to Cloudflare via a GUI” was a very common request. Customers we interviewed typically wanted a simple way to upload a list of ‘from,to,response code’ without having to write a single line of code. And that’s what we are announcing today.
Bulk Redirects is now available for all Cloudflare plans. It is an account/organization-level product capable of supporting hundreds of thousands of URL redirects, all configured via the dashboard without having to write a single line of code.
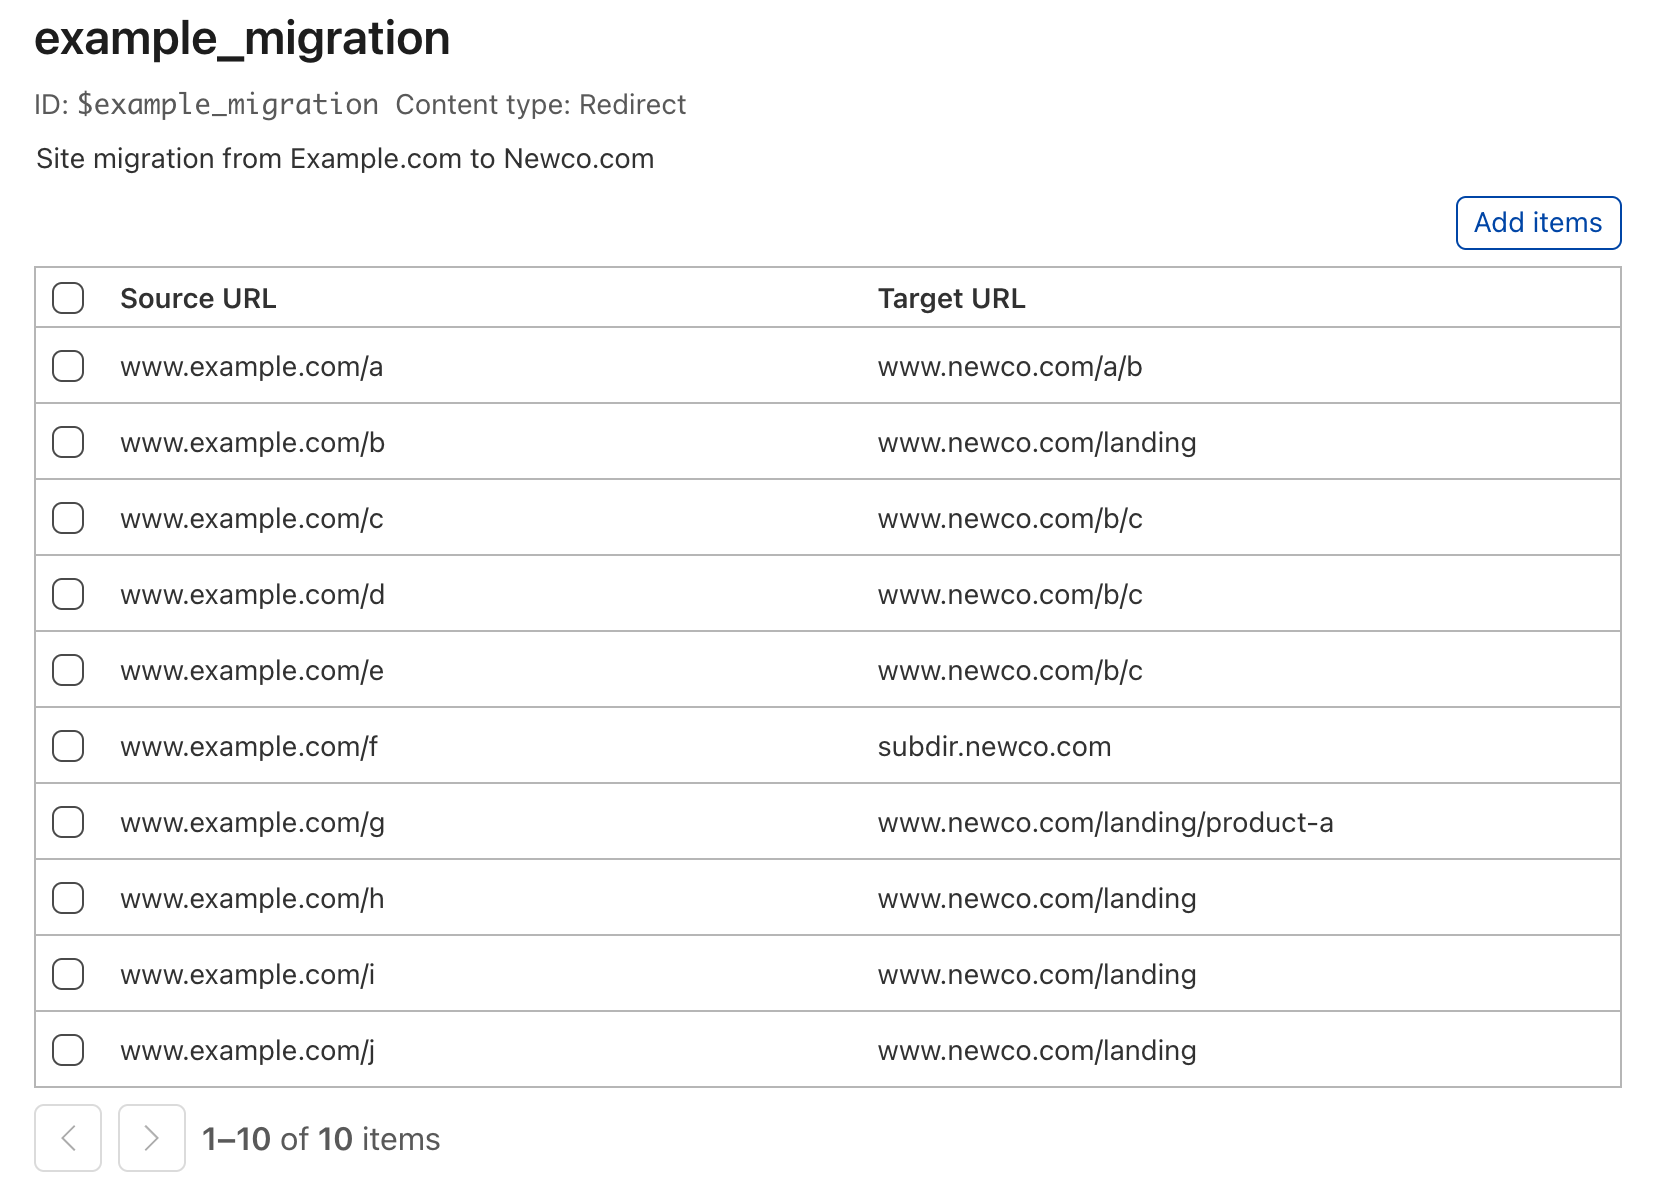
The system is implemented in two parts. The first part is the Bulk Redirect List. This is effectively the redirect map, or ‘edge dictionary’, where users can upload their URL redirects:
Each URL redirect within the list contains three main elements. The first two elements are Source URL (the URL we are looking for) and TargetURL (the URL we are going to redirect matching traffic to).
There is also the Status code. This is the ‘type’ of redirect. In addition to 301 (Moved Permanently) and 302 (Moved Temporarily) redirects, we have added support for the newer 307 (Temporary Redirect) and 308 (Permanent Redirect) redirect status codes.
We have added support for specifying destination ports within the Target URL field also, allowing URL redirects to non-standard ports, e.g., “Target URL: www.example.com:8443”.
If you have many URL redirects, you can upload them via a CSV file.
There are also four additional parameters available for each individual URL redirect.
Firstly, we have added two options to replace the ambiguity and confusion caused by the use of asterisks as wildcards. Take this source URL as an example: *.example.com/a/b. Would you expect www.example.com/a/b to match? How about example.com/a/b, or www.example.com/path*? Asterisks used as wildcards cause confusion and misunderstanding, and also increase the cost of implementation and maintenance from an engineering perspective. Therefore, we are not implementing them in Bulk Redirects.
Instead, we have added two discrete options: Include subdomains and Subpath matching. The Include subdomains option, once enabled, will match all subdomains to the left of the domain portion of the URL as well as the domain specified. For example, if there is a URL redirect with a source URL of example.com/a then traffic to b.example.com/a and c.b.example.com/a will also be redirected.
The Subpath matching option focuses on the opposite end of the URL. If this option is enabled, the redirect applies to the URL as well as all its subpaths. For example, if we have a URL redirect on www.example.com/foo with subpath matching enabled, we will match on that specific URL as well as all subpaths, e.g., www.example.com/foo/a, www.example.com/foo/a/, ` www.example.com/foo/a/b/c`, etc., but not www.example.com/foobar.
These options provide a tremendous amount of flexibility and granularity for each URL redirect. However, for most use cases only the source URL, target URL, and status code options will need to be set.
Secondly, we have added two options relating to retaining portions of the original HTTP request: Preserve path suffix and Preserve query string. If subpath matching is enabled, Preserve path suffix can be used to copy the URI path from the originally requested URL and add it to the destination URL. For example, if there is a URL redirect of Source URL: example.co.uk, Target URL: www.example.com/a, then requests to example.co.uk/target will be redirected to www.example.com/a/target with both options enabled. Preserve query string can be used independently of the other options, and carries forward the URI query from the originally requested URL to the new URL.
Lists by themselves do not provide any redirection, they are simply the ‘lookup table’. To enable them we need to reference them via a Bulk Redirect Rule.
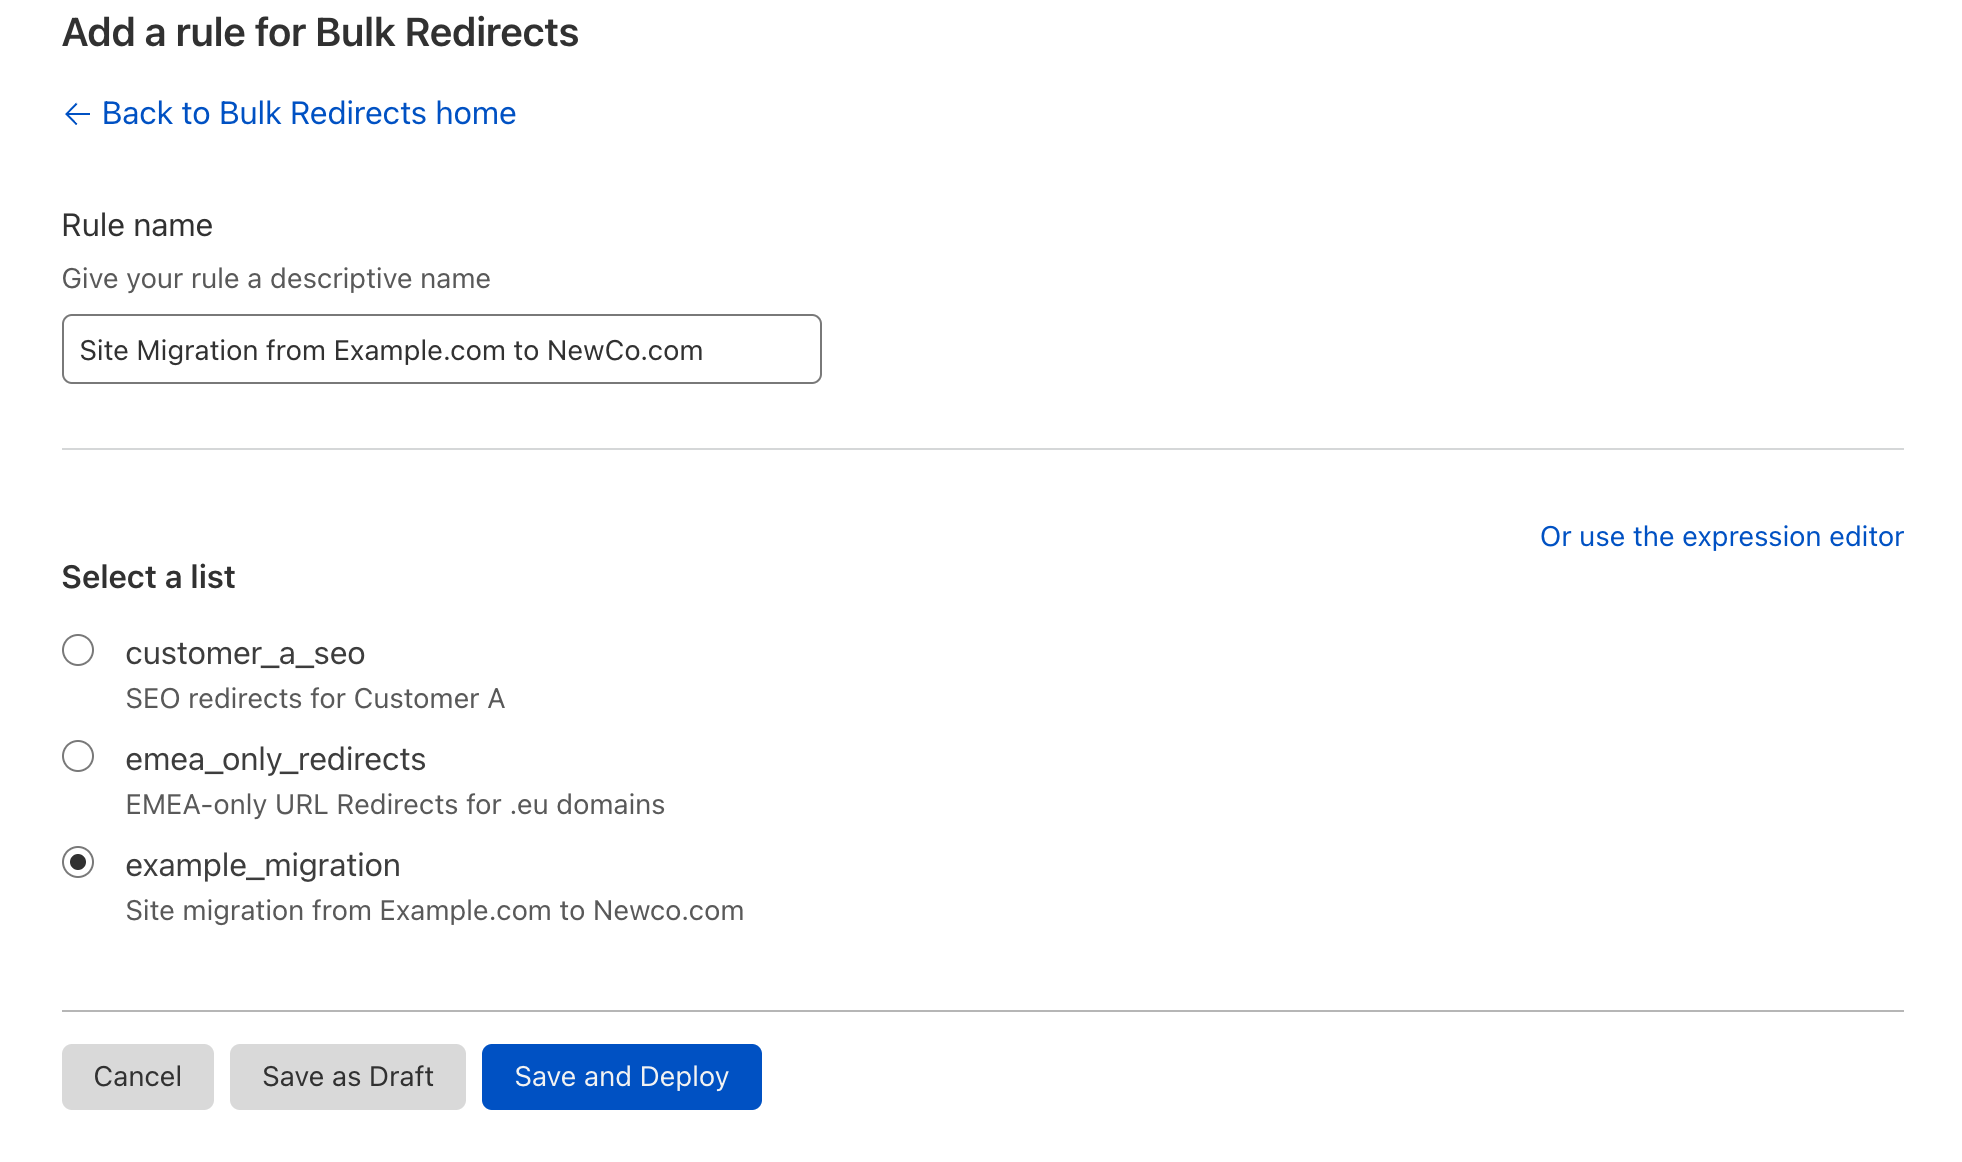
The rules themselves are very simple. By default, the user experience is to provide a name for the rule, a description, and select the Bulk Redirect List that should be invoked.
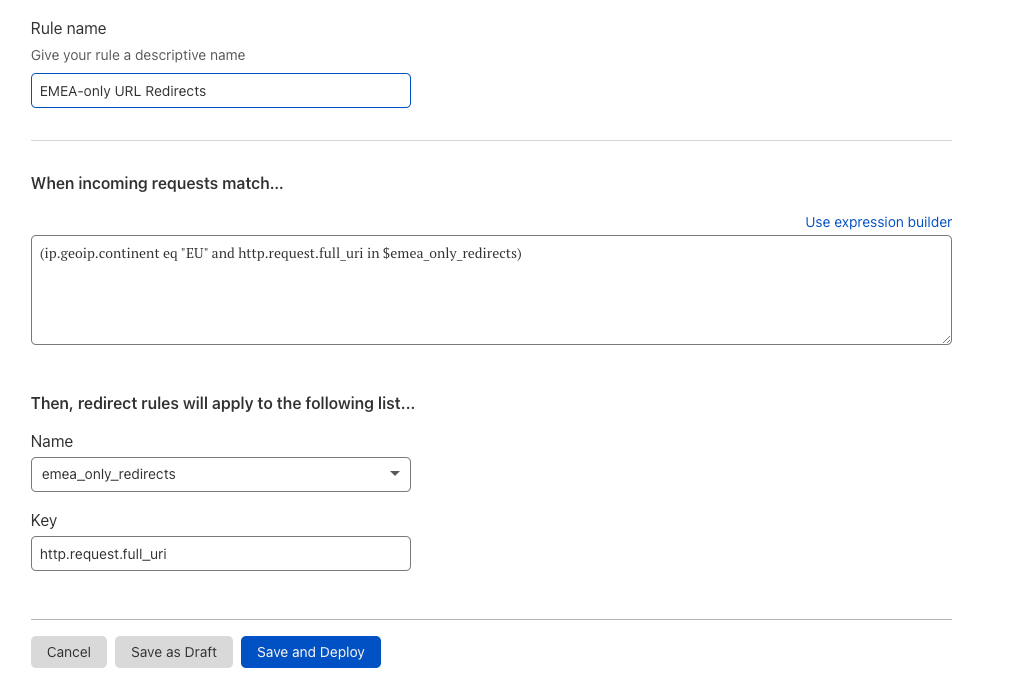
For users who require more granularity and control there are additional settings available under the Advanced options toggle. Within this section there are two editable sections: Expression and Key.
The first field, Expression,specifies the conditions that must be met in order for the rule to run. By default, all URL redirects of the specified list will apply.
The second field, Key, is closely related to the expression. The key is used in combination with the specified list to select the URL redirect to apply. The field used for the key should always be the same as the field used in the expression, i.e., the key should be http.request.full_uri if the field in the expression is http.request.full_uri, or conversely, the key should be raw.http.request.full_uri if the field in the expression is raw.http.request.full_uri.
There are two main use cases for modifying these settings. Firstly, users can edit these options to increase specificity in the trigger, e.g., ip.src.country == "GB" and http.request.full_uri in $redirect_list. This is useful for ensuring Bulk Redirect Lists are only applied when a visitor comes from specific countries, subnets, or ASNs — or also only applying a URL redirect list if the visitor is a verified bot, or the bot score is >35.
Secondly, users can edit these options to amend the URL being matched and used as a lookup in the given list, i.e., the user may choose to have URL redirects in their list(s) specifically for URLs that would be normalized, e.g., URLs containing specific percent-encoding. To ensure these URL redirects still trigger, the settings in Advanced options should be used to edit the expression and key to use the raw.http.request.full_uri field instead.
Automating via the API
Another way to manage bulk redirects is via our API. Customers wishing to automate the addition of bulk redirects can use the API to either simply add URL redirects to an existing list, or automate the entire workflow — creating a list, adding URL redirects to the list, and enabling the list via a new redirect rule.
There are three main calls when creating bulk redirects via the API:
Create the redirect list
Load with URL redirects
Enable via a rule (You will also need to create the ruleset if doing this for the first time).
For step 1, first create a mass redirect list via the API call:
curl --location --request POST 'https://api.cloudflare.com/client/v4/accounts/<ACCOUNT_ID>/rules/lists' \
--header 'X-Auth-Email: <EMAIL_ADDRESS>' \
--header 'Content-Type: application/json' \
--header 'X-Auth-Key: <API_KEY>' \
--data-raw '{
 "name": "my_redirect_list_2",
 "description": "My redirect list 2",
 "kind": "redirect"
}'
Capture the value of “id”, as this is the list id we will then add URL redirects to.
Next, in step 2 we will add URL redirects to our newly created list by executing a POST call to the id we captured previously – with our URL redirects in the body:
In step 3 we enable this list by creating a new mass redirect rule within the mass redirect account-level ruleset.
Note, if this is the first time you are creating a redirect rule you will need to use a different API call to create the ruleset. See the documentation here for more details. All subsequent updates to the rulesets are made by calls similar to below.
Firstly, we need to find our account-level rulesets id. To do this we need to get a list of all account-level rulesets and look for the ruleset with the phase http_request_redirect:
{
   "result": [
       {
           "id": "efb7b8c949ac4650a09736fc376e9aee",
           "name": "Cloudflare Managed Ruleset",
           "description": "Created by the Cloudflare security team, this ruleset is designed to provide fast and effective protection for all your applications. It is frequently updated to cover new vulnerabilities and reduce false positives.",
           "source": "firewall_managed",
           "kind": "managed",
           "version": "34",
           "last_updated": "2021-10-25T18:33:27.512161Z",
           "phase": "http_request_firewall_managed"
       },
       {
           "id": "4814384a9e5d4991b9815dcfc25d2f1f",
           "name": "Cloudflare OWASP Core Ruleset",
           "description": "Cloudflare's implementation of the Open Web Application Security Project (OWASP) ModSecurity Core Rule Set. We routinely monitor for updates from OWASP based on the latest version available from the official code repository",
           "source": "firewall_managed",
           "kind": "managed",
           "version": "33",
           "last_updated": "2021-10-25T18:33:29.023088Z",
           "phase": "http_request_firewall_managed"
       },
       {
           "id": "5ff4477e596448749d67da859230ac3d",
           "name": "My redirect ruleset",
           "description": "",
           "kind": "root",
           "version": "1",
           "last_updated": "2021-12-04T06:32:58.058744Z",
           "phase": "http_request_redirect"
       }
   ],
   "success": true,
   "errors": [],
   "messages": []
}
Our redirect ruleset is at the bottom of the output. Next we will add our new bulk redirect rule to this ruleset:
With those API calls executed, our new list is created, loaded with URL redirects and enabled by the bulk redirect rule. Visitors to the URLs specified in our list will now be redirected appropriately.
Account-level benefits
One of the driving forces behind this product is the desire to make life easier for those customers with a large number of zones on Cloudflare. For these customers, URL redirects are a pain point when using Page Rules, as they need to navigate into each zone and configure URL redirects one at a time. This doesn’t scale very well.
Bulk Redirects add real value for customers in this situation. Instead of having to navigate into 400 zones and create one or two Page Rules for each, an administrator can now create and upload a single Bulk Redirect List, which contains all the URL redirects for the zones under management.
This means that if the customer simply wants 399 of those 400 zones to redirect to the “primary zone”, they can create a bulk redirect list with 399 entries, all pointing to example.com, and enable the Subpath matching and Include subdomains options on each. This vastly simplifies the management of the estate.
The same premise also applies to SSL for SaaS customers. For example, if example.com has 20 custom hostnames in their zone, customers can now create a Bulk Redirect List and Rule for each custom hostname, grouping each customer’s URL redirects into their own logical buckets.
Bulk Redirects is a game changer for companies with a large number of zones and customers under management.
Allowances
Bulk Redirects are available for all accounts. The packaging model for Bulk Redirects closely resembles that of “IP Lists”. Accounts are entitled to a set number of Edge Rules (from which “Bulk Redirect Rules” draws down), Bulk Redirect Lists, and URL Redirects depending on the highest Cloudflare plan within their account.
Feature
Enterprise
Business
Pro
Free
Edge Rules (for use of Bulk Redirect Rules)
50+
15
15
15
Bulk Redirect Lists
25+
5
5
5
URL Redirects
10,000+
500
500
20
For example, an account with ten zones, all on the Free plan, would be entitled to 15 Edge Rules, 5 Bulk Redirect Lists, and 20 URL Redirects that can be stored within those lists.
An account with one Pro zone and 2 Free plan zones would be entitled to 15 Edge Rules, 5 Bulk Redirect Lists, and 500 URL Redirects that can be stored within those lists.
Enterprise customers have a default of 10,000 URL Redirects to be used across 25 lists. However, these numbers are negotiable on enquiry.
Planned enhancements
We intend to make a number of incremental improvements to the product in the coming months, specifically to the list experience to allow for the editing of URL redirects and also for searching within lists.
In the near future we intend to bring to market a product to fulfill the other common request for URL redirects, and deliver ‘Dynamic URL Redirects’. Whilst Bulk Redirects supports hundreds of thousands of URL redirects, those URL redirects are relatively prescriptive — from a.com/b to b.com/a, for example. There is still a requirement for supporting more complex, rich URL redirects, e.g., device-specific URL redirects, country-specific URL redirects, URL redirects that allow regular expressions in their target URL, and so forth. We aspire to offer a full range of functionality to support as many use cases as possible.
Try it now
Bulk Redirects can be used to improve operations, simplify complex configurations, and ease website management, amongst many other use cases. Try out Bulk Redirects yourself today.
After initially providing our customers control over the HTTP-layer DDoS protection settings earlier this year, we’re now excited to extend the control our customers have to the packet layer. Using these new controls, Cloudflare Enterprise customers using the Magic Transit and Spectrum services can now tune and tweak their L3/4 DDoS protection settings directly from the Cloudflare dashboard or via the Cloudflare API.
The new functionality provides customers control over two main DDoS rulesets:
Network-layer DDoS Protectionruleset — This ruleset includes rules to detect and mitigate DDoS attacks on layer 3/4 of the OSI model such as UDP floods, SYN-ACK reflection attacks, SYN Floods, and DNS floods. This ruleset is available for Spectrum and Magic Transit customers on the Enterprise plan.
Advanced TCP Protectionruleset — This ruleset includes rules to detect and mitigate sophisticated out-of-state TCP attacks such as spoofed ACK Floods, Randomized SYN Floods, and distributed SYN-ACK Reflection attacks. This ruleset is available for Magic Transit customers only.
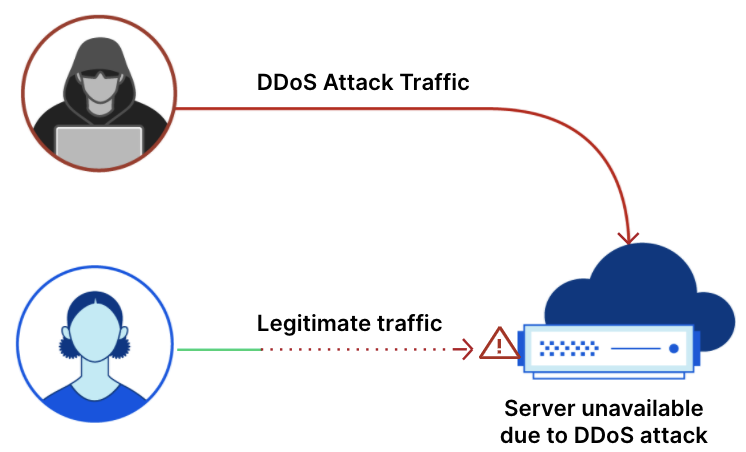
A Distributed Denial of Service (DDoS) attack is a type of cyberattack that aims to disrupt the victim’s Internet services. There are many types of DDoS attacks, and they can be generated by attackers at different layers of the Internet. One example is the HTTP flood. It aims to disrupt HTTP application servers such as those that power mobile apps and websites. Another example is the UDP flood. While this type of attack can be used to disrupt HTTP servers, it can also be used in an attempt to disrupt non-HTTP applications. These include TCP-based and UDP-based applications, networking services such as VoIP services, gaming servers, cryptocurrency, and more.
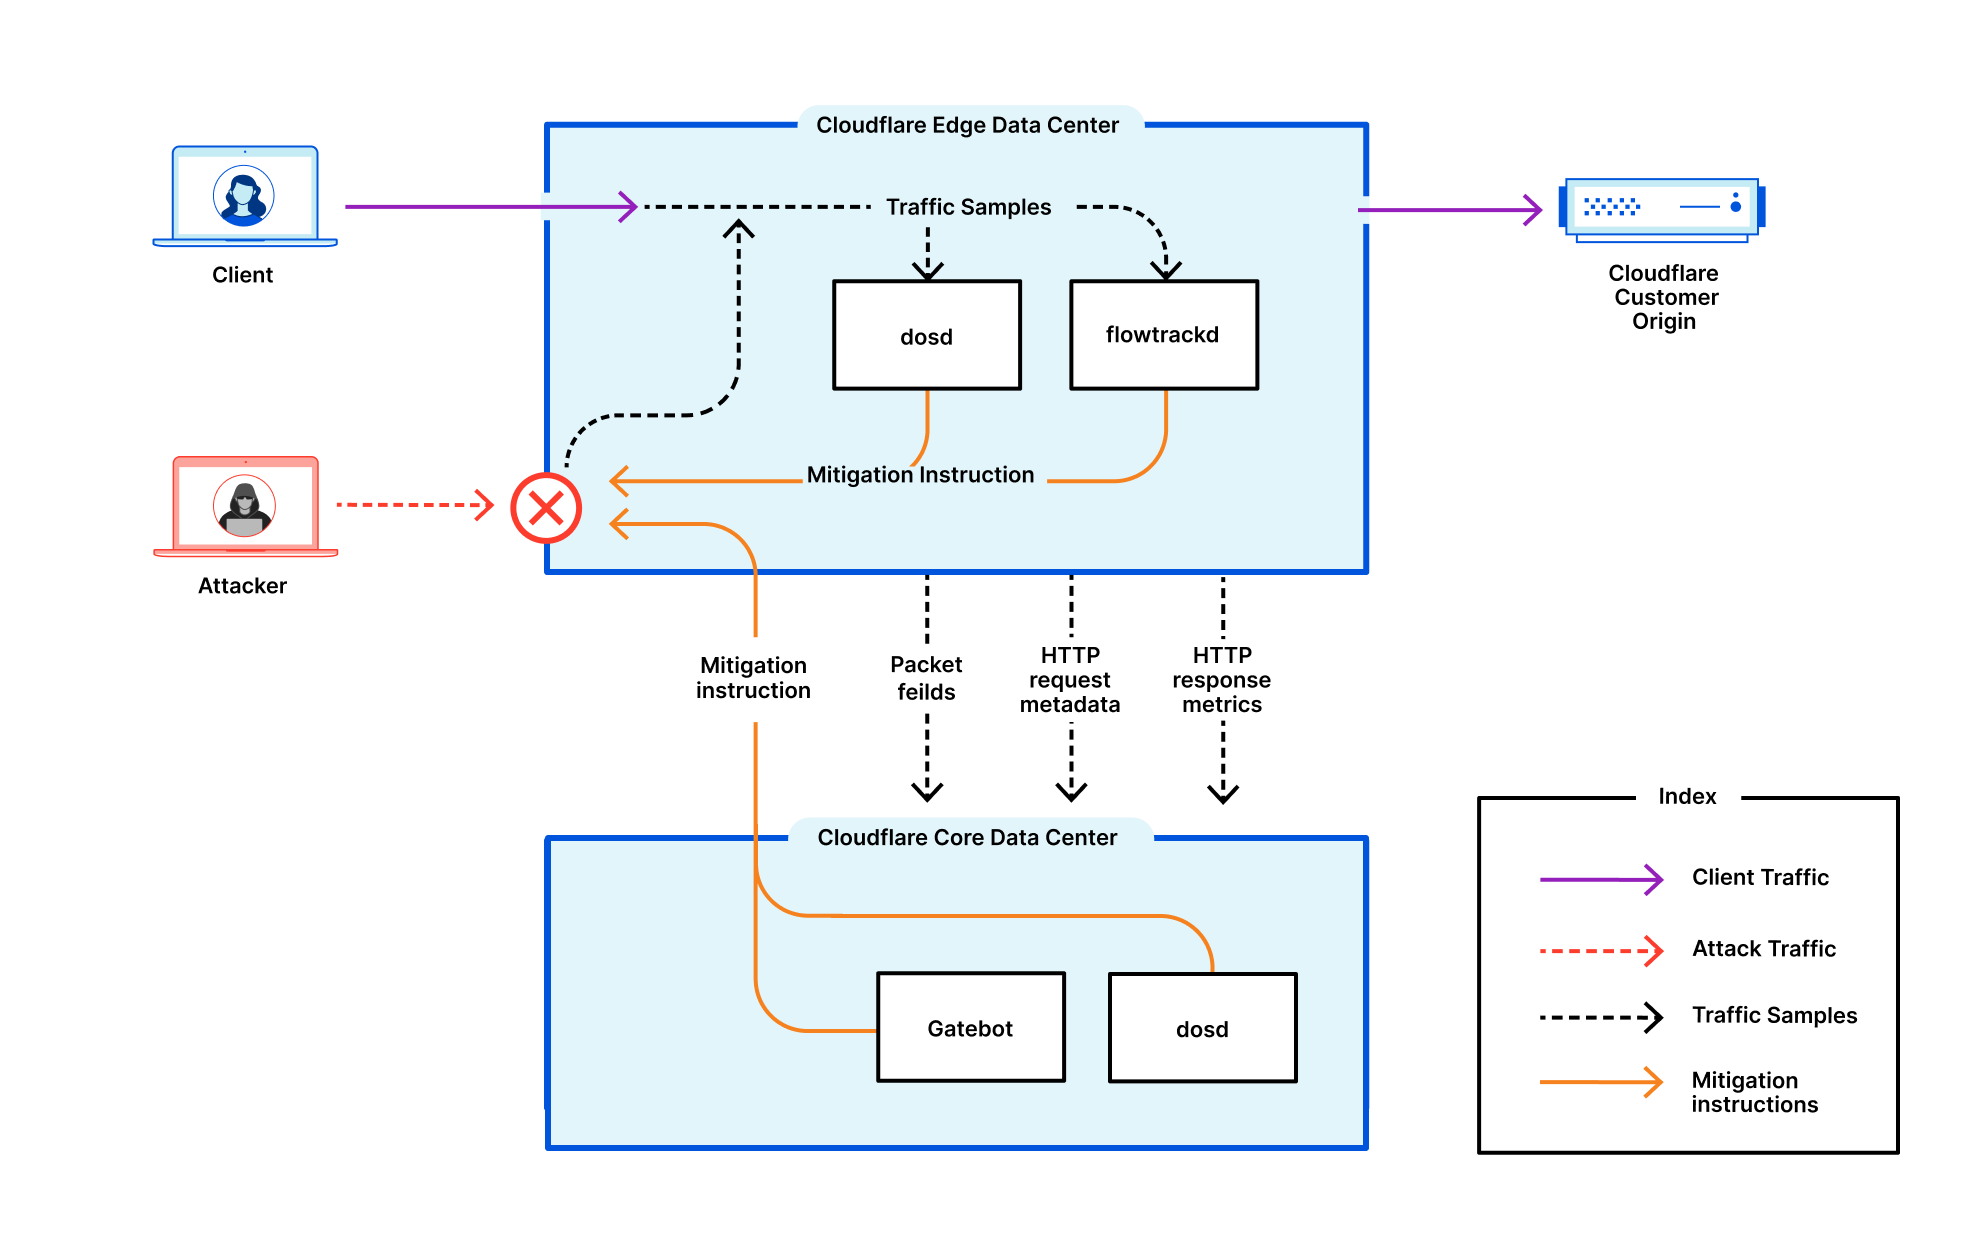
To defend organizations against DDoS attacks, we built and operate software-defined systems that run autonomously. They automatically detect and mitigate DDoS attacks across our entire network. You can read more about our autonomous DDoS protection systems and how they work in our deep-dive technical blog post.
Unmetered and unlimited DDoS Protection
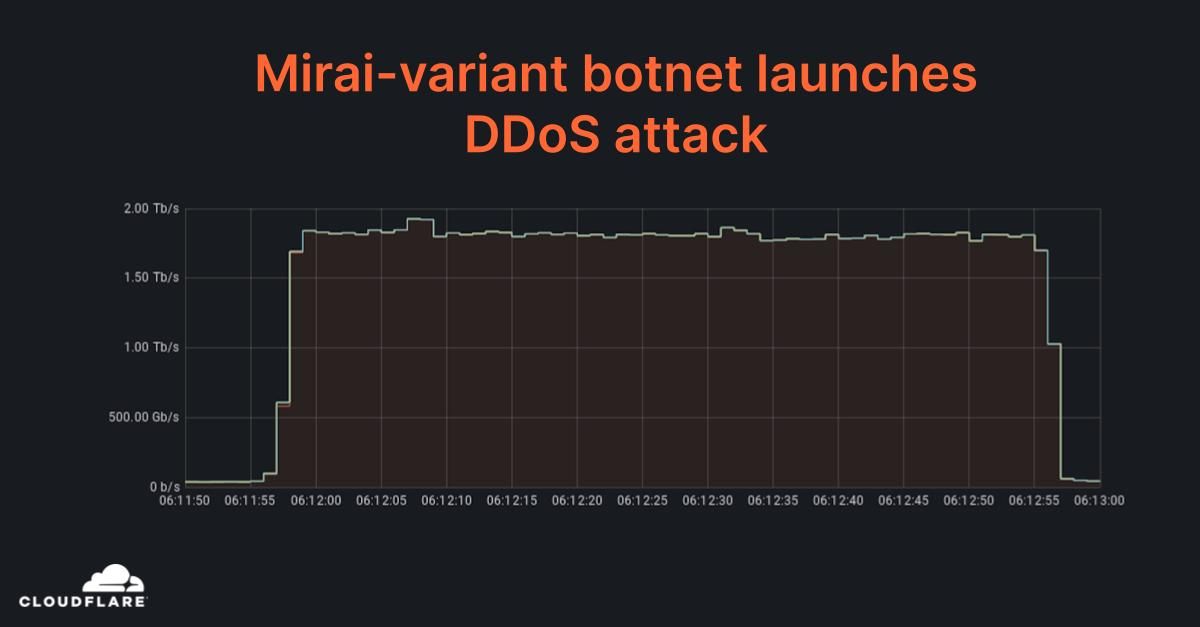
The level of protection that we offer is unmetered and unlimited — It is not bounded by the size of the attack, the number of the attacks, or the duration of the attacks. This is especially important these days because as we’ve recently seen, attacks are getting larger and more frequent. Consequently, in Q3, network-layer attacks increased by 44% compared to the previous quarter. Furthermore, just recently, our systems automatically detected and mitigated a DDoS attack that peaked just below 2 Tbps — the largest we’ve seen to date.
Mirai botnet launched an almost 2 Tbps DDoS attack
You can think of our autonomous DDoS protection systems as groups (rulesets) of intelligent rules. There are rulesets of HTTP DDoS Protection rules, Network-layer DDoS Protection rules and Advanced TCP Protection rules. In this blog post, we will cover the latter two rulesets. We’ve already covered the former in the blog post How to customize your HTTP DDoS protection settings.
Cloudflare L3/4 DDoS Managed Rules
In the Network-layer DDoS Protection rulesets, each rule has a unique set of conditional fingerprints, dynamic field masking, activation thresholds, and mitigation actions. These rules are managed (by Cloudflare), meaning that the specifics of each rule is curated in-house by our DDoS experts. Before deploying a new rule, it is first rigorously tested and optimized for mitigation accuracy and efficiency across our entire global network.
In the Advanced TCP Protection ruleset, we use a novel TCP state classification engine to identify the state of TCP flows. The engine powering this ruleset is flowtrackd — you can read more about it in our announcement blog post. One of the unique features of this system is that it is able to operate using only the ingress (inbound) packet flows. The system sees only the ingress traffic and is able to drop, challenge, or allow packets based on their legitimacy. For example, a flood of ACK packets that don’t correspond to open TCP connections will be dropped.
How attacks are detected and mitigated
Sampling
Initially, traffic is routed through the Internet via BGP Anycast to the nearest Cloudflare edge data center. Once the traffic reaches our data center, our DDoS systems sample it asynchronously allowing for out-of-path analysis of traffic without introducing latency penalties. The Advanced TCP Protection ruleset needs to view the entire packet flow and so it sits inline for Magic Transit customers only. It, too, does not introduce any latency penalties.
Analysis & mitigation
The analysis for the Advanced TCP Protection ruleset is straightforward and efficient. The system qualifies TCP flows and tracks their state. In this way, packets that don’t correspond to a legitimate connection and its state are dropped or challenged. The mitigation is activated only above certain thresholds that customers can define.
The analysis for the Network-layer DDoS Protection ruleset is done using data streaming algorithms. Packet samples are compared to the conditional fingerprints and multiple real-time signatures are created based on the dynamic masking. Each time another packet matches one of the signatures, a counter is increased. When the activation threshold is reached for a given signature, a mitigation rule is compiled and pushed inline. The mitigation rule includes the real-time signature and the mitigation action, e.g., drop.
Example
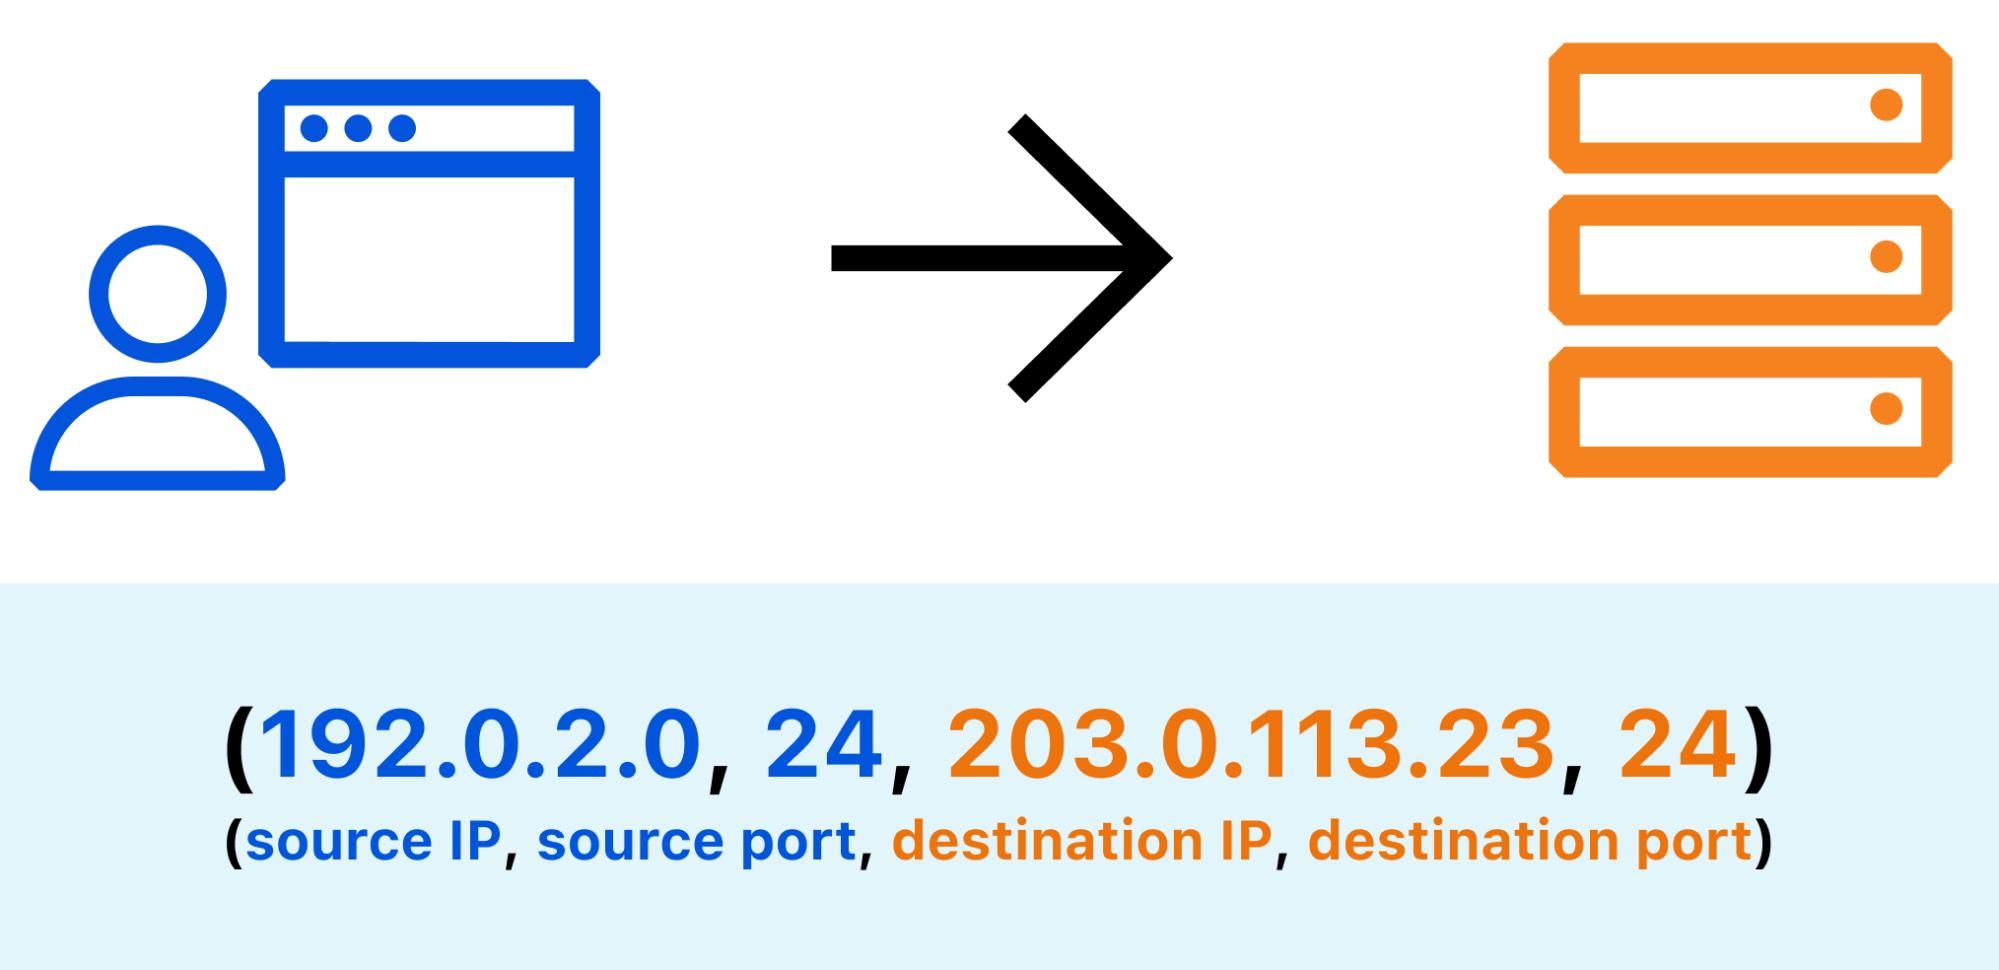
As a simple example, one fingerprint could include the following fields: source IP, source port, destination IP, and the TCP sequence number. A packet flood attack with a fixed sequence number would match the fingerprint and the counter would increase for every packet match until the activation threshold is exceeded. Then a mitigation action would be applied.
However, in the case of a spoofed attack where the source IP addresses and ports are randomized, we would end up with multiple signatures for each combination of source IP and port. Assuming a sufficiently randomized/distributed attack, the activation thresholds would not be met and mitigation would not occur. For this reason, we use dynamic masking, i.e. ignoring fields that may not be a strong indicator of the signature. By masking (ignoring) the source IP and port, we would be able to match all the attack packets based on the unique TCP sequence number regardless of how randomized/distributed the attack is.
Configuring the DDoS Protection Settings
For now, we’ve only exposed a handful of the Network-layer DDoS protection rules that we’ve identified as the ones most prone to customizations. We will be exposing more and more rules on a regular basis. This shouldn’t affect any of your traffic.
Overriding the sensitivity level and mitigation action
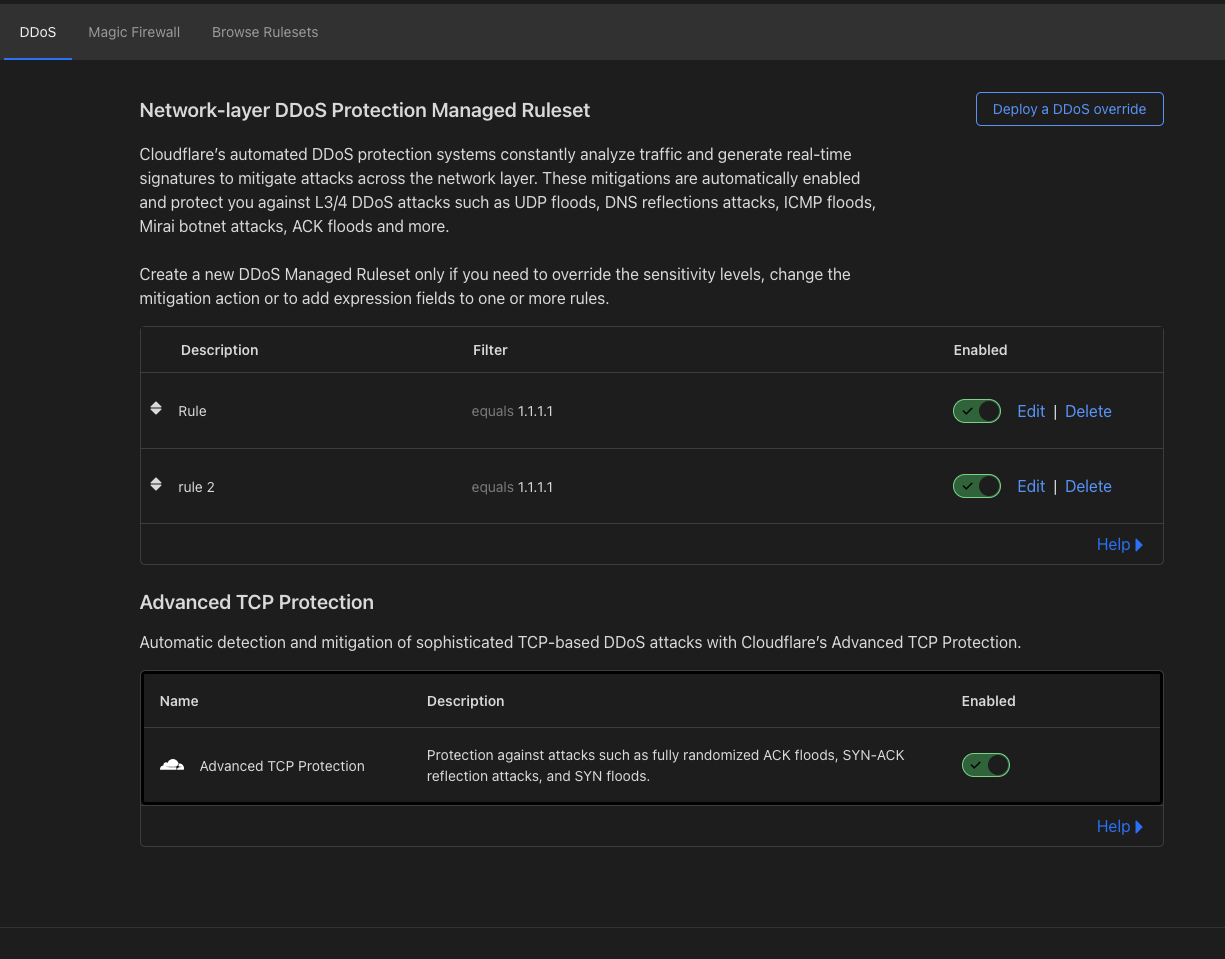
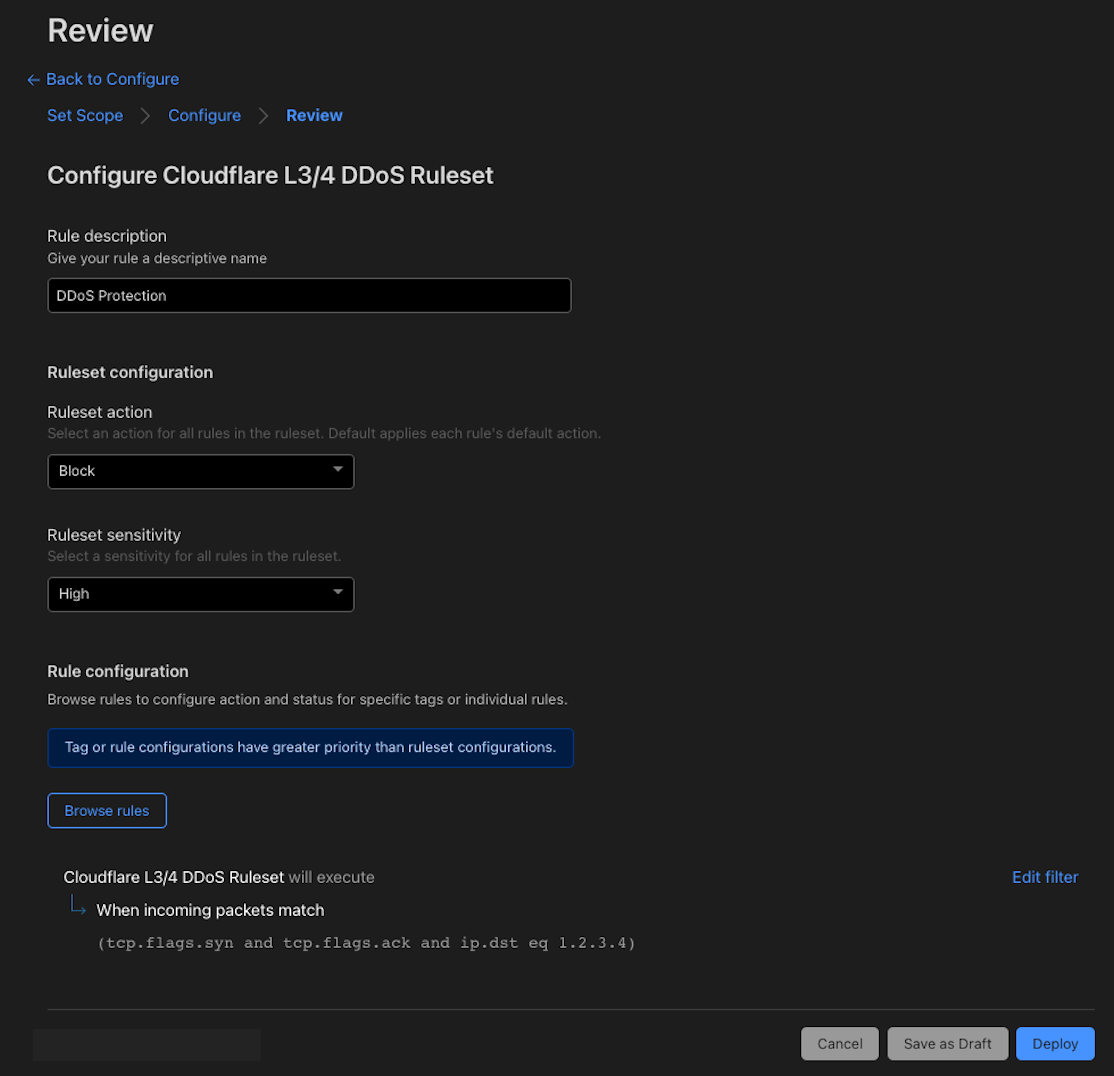
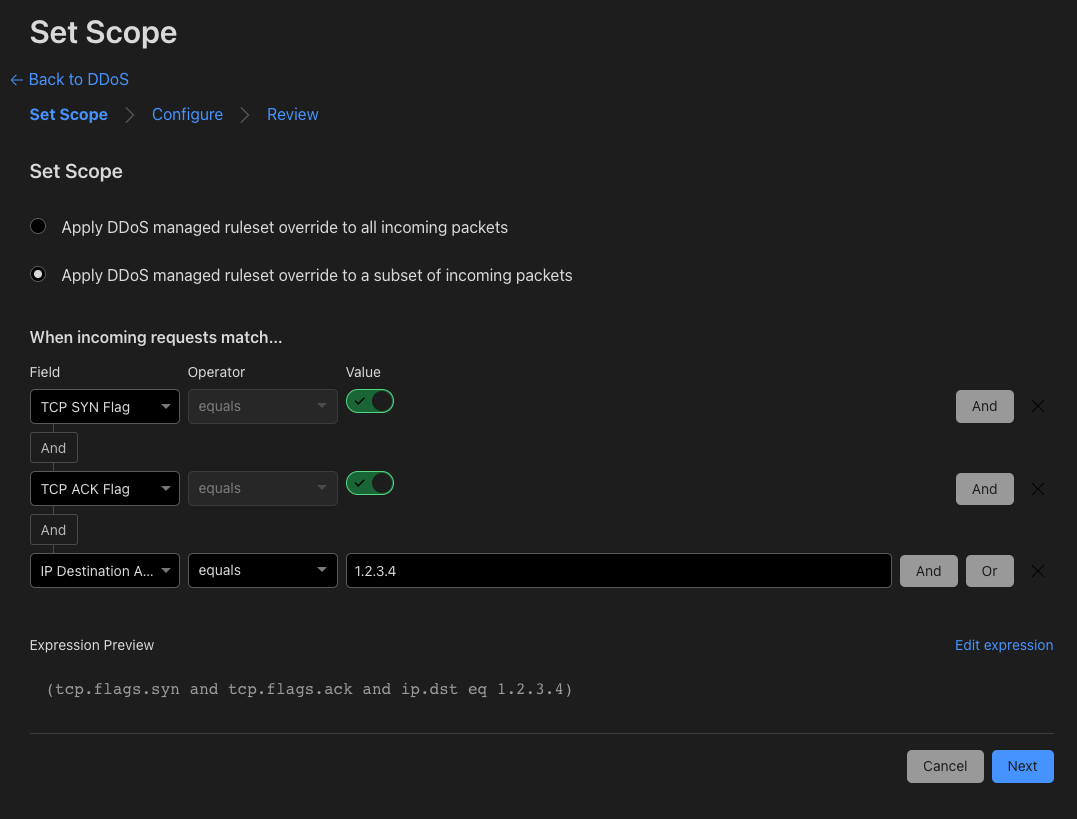
For the Network-layer DDoS Protection ruleset, for each of the available rules, you can override the sensitivity level (activation threshold), customize the mitigation action, and apply expression filters to exclude/include traffic from the DDoS protection system based on various packet fields. You can create multiple overrides to customize the protection for your network and your various applications.
Configuring expression fields for the DDoS Managed Rules to match on
In the past, you’d have to go through our support channels to customize the rules. In some cases, this may have taken longer to resolve than desired. With today’s announcement, you can tailor and fine-tune the settings of our autonomous edge system by yourself to quickly improve the accuracy of the protection for your specific network needs.
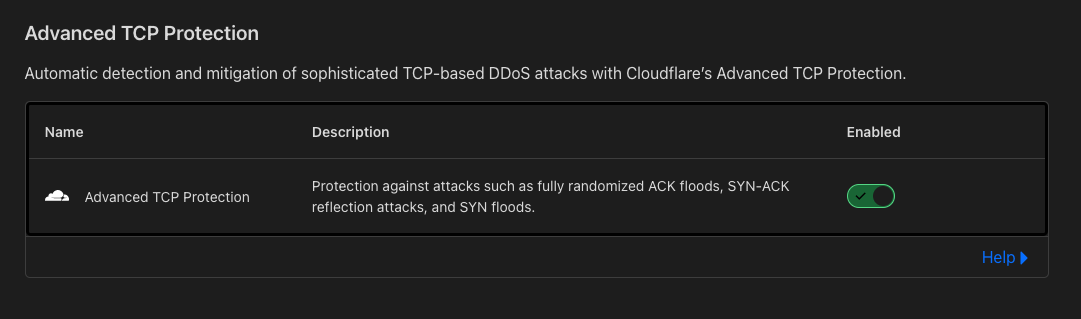
For the Advanced TCP Protection ruleset, for now, we’ve only exposed the ability to enable or disable it as a whole in the dashboard. To enable or disable the ruleset per IP prefix, you must use the API. At this time, when initially onboarding to Cloudflare, the Cloudflare team must first create a policy for you. After onboarding, if you need to change the sensitivity thresholds, use Monitor mode, or add filter expressions you must contact Cloudflare Support. In upcoming releases, this too will be available via the dashboard and API without requiring help from our Support team.
Pre-existing customizations
If you previously contacted Cloudflare Support to apply customizations, your customizations have been preserved, and you can visit the dashboard to view the settings of the Network-layer DDoS Protection ruleset and change them if you need. If you require any changes to your Advanced TCP Protection customizations, please reach out to Cloudflare Support.
If so far you didn’t have the need to customize this protection, there is no action required on your end. However, if you would like to view and customize your DDoS protection settings, follow this dashboard guide or review the API documentation to programmatically configure the DDoS protection settings.
Helping Build a Better Internet
At Cloudflare, everything we do is guided by our mission to help build a better Internet. The DDoS team’s vision is derived from this mission: our goal is to make the impact of DDoS attacks a thing of the past. Our first step was to build the autonomous systems that detect and mitigate attacks independently. Done. The second step was to expose the control plane over these systems to our customers (announced today). Done. The next step will be to fully automate the configuration with an auto-pilot feature — training the systems to learn your specific traffic patterns to automatically optimize your DDoS protection settings. You can expect many more improvements, automations, and new capabilities to keep your Internet properties safe, available, and performant.
At the end of 2020, Cloudflare empowered organizations to start building a private network on top of our network. Using Cloudflare Tunnel on the server side, and Cloudflare WARP on the client side, the need for a legacy VPN was eliminated. Fast-forward to today, and thousands of organizations have gone on this journey with us — unplugging their legacy VPN concentrators, internal firewalls, and load balancers. They’ve eliminated the need to maintain all this legacy hardware; they’ve dramatically improved speeds for end users; and they’re able to maintain Zero Trust rules organization-wide.
We started with TCP, which is powerful because it enables an important range of use cases. However, to truly replace a VPN, you need to be able to cover UDP, too. Starting today, we’re excited to provide early access to UDP on Cloudflare’s Zero Trust platform. And even better: as a result of supporting UDP, we can offer Internal DNS — so there’s no need to migrate thousands of private hostnames by hand to override DNS rules. You can get started with Cloudflare for Teams for free today by signing up here; and if you’d like to join the waitlist to gain early access to UDP and Internal DNS, please visit here.
The topology of a private network on Cloudflare
Building out a private network has two primary components: the infrastructure side, and the client side.
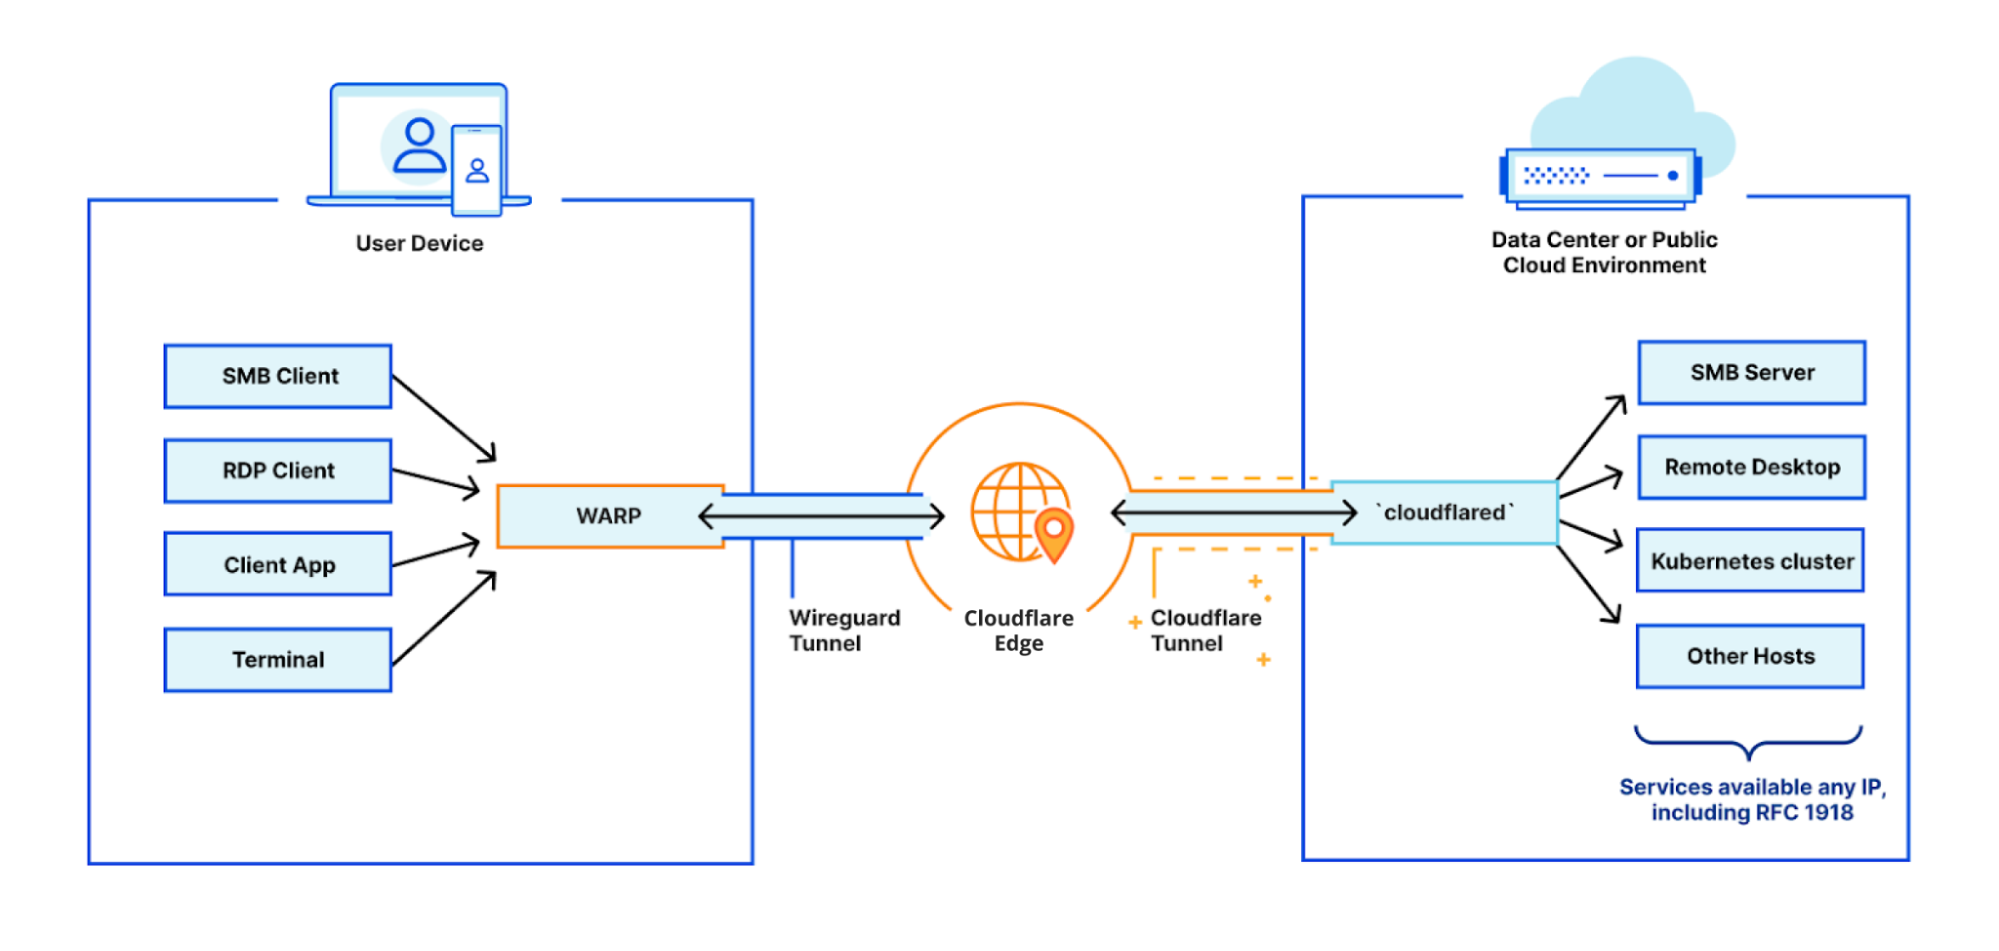
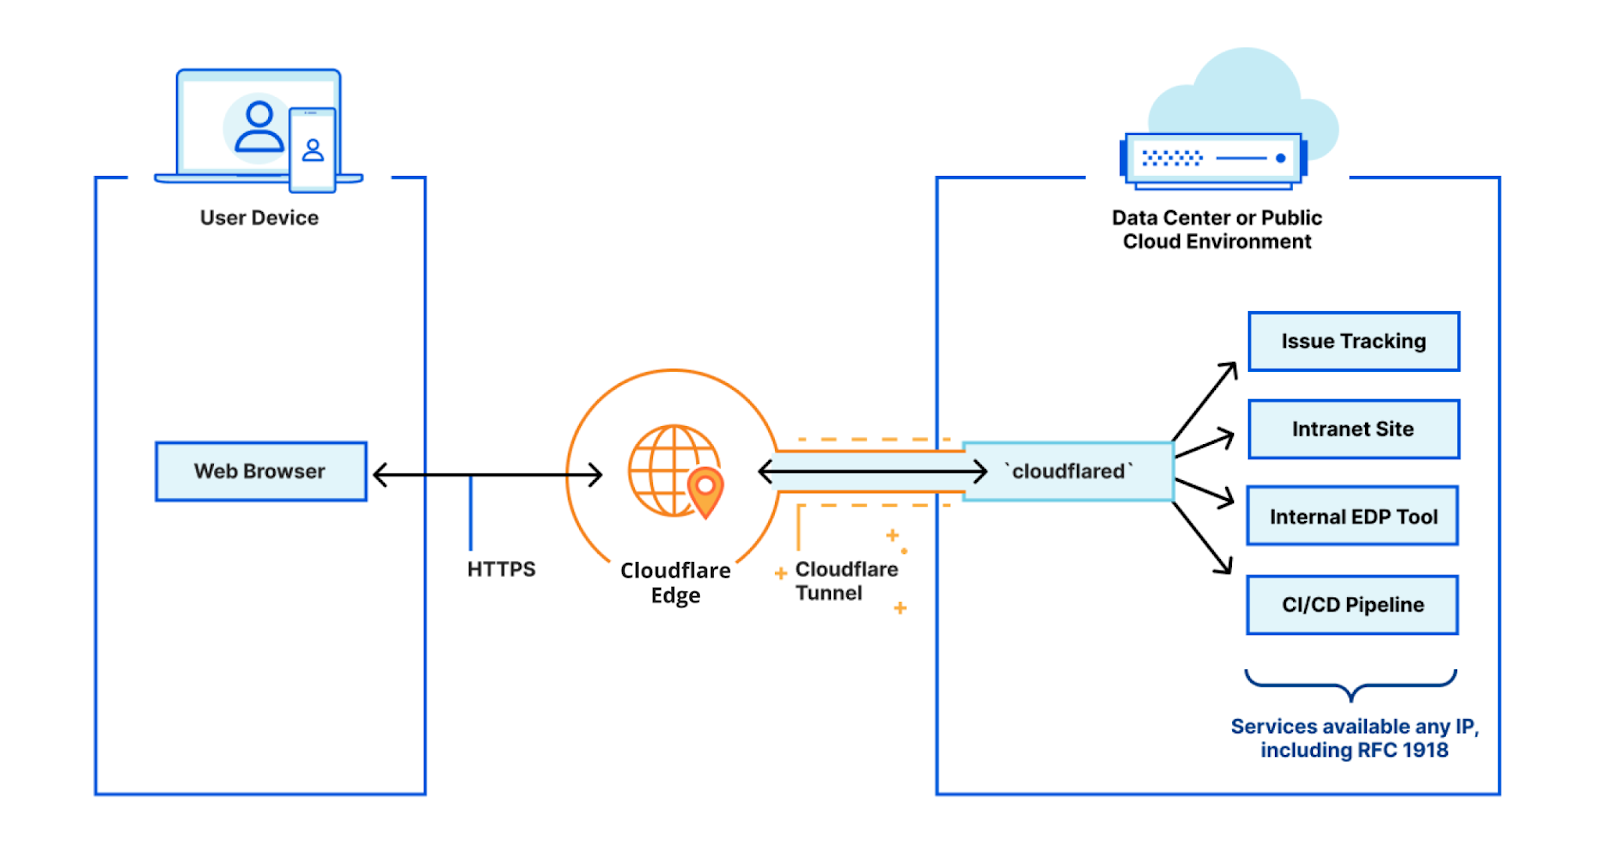
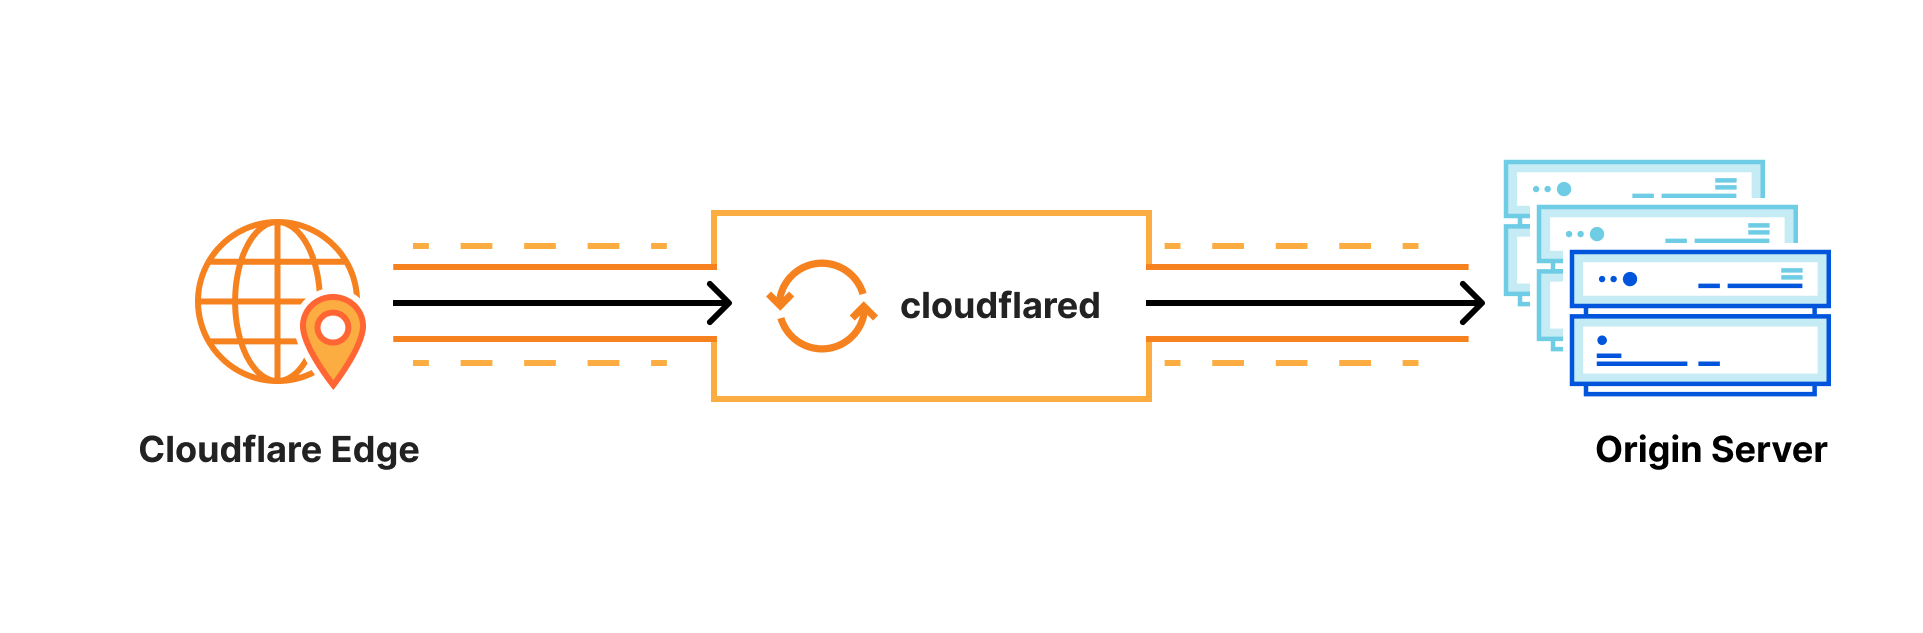
The infrastructure side of the equation is powered by Cloudflare Tunnel, which simply connects your infrastructure (whether that be a singular application, many applications, or an entire network segment) to Cloudflare. This is made possible by running a simple command-line daemon in your environment to establish multiple secure, outbound-only, load-balanced links to Cloudflare. Simply put, Tunnel is what connects your network to Cloudflare.
On the other side of this equation, we need your end users to be able to easily connect to Cloudflare and, more importantly, your network. This connection is handled by our robust device client, Cloudflare WARP. This client can be rolled out to your entire organization in just a few minutes using your in-house MDM tooling, and it establishes a secure, WireGuard-based connection from your users’ devices to the Cloudflare network.
Now that we have your infrastructure and your users connected to Cloudflare, it becomes easy to tag your applications and layer on Zero Trust security controls to verify both identity and device-centric rules for each and every request on your network.
Up until now though, only TCP was supported.
Extending Cloudflare Zero Trust to support UDP
Over the past year, with more and more users adopting Cloudflare’s Zero Trust platform, we have gathered data surrounding all the use cases that are keeping VPNs plugged in. Of those, the most common need has been blanket support for UDP-based traffic. Modern protocols like QUIC take advantage of UDP’s lightweight architecture — and at Cloudflare, we believe it is part of our mission to advance these new standards to help build a better Internet.
Today, we’re excited to open an official waitlist for those who would like early access to Cloudflare for Teams with UDP support.
What is UDP and why does it matter?
UDP is a vital component of the Internet. Without it, many applications would be rendered woefully inadequate for modern use. Applications which depend on near real time communication such as video streaming or VoIP services are prime examples of why we need UDP and the role it fills for the Internet. At their core, however, TCP and UDP achieve the same results — just through vastly different means. Each has their own unique benefits and drawbacks, which are always felt downstream by the applications that utilize them.
Here’s a quick example of how they both work, if you were to ask a question to somebody as a metaphor. TCP should look pretty familiar: you would typically say hi, wait for them to say hi back, ask how they are, wait for their response, and then ask them what you want.
UDP, on the other hand, is the equivalent of just walking up to someone and asking what you want without checking to make sure that they’re listening. With this approach, some of your question may be missed, but that’s fine as long as you get an answer.
Like the conversation above, with UDP many applications actually don’t care if some data gets lost; video streaming or game servers are good examples here. If you were to lose a packet in transit while streaming, you wouldn’t want the entire stream to be interrupted until this packet is received — you’d rather just drop the packet and move on. Another reason application developers may utilize UDP is because they’d prefer to develop their own controls around connection, transmission, and quality control rather than use TCP’s standardized ones.
For Cloudflare, end-to-end support for UDP-based traffic will unlock a number of new use cases. Here are a few we think you’ll agree are pretty exciting.
Internal DNS Resolvers
Most corporate networks require an internal DNS resolver to disseminate access to resources made available over their Intranet. Your Intranet needs an internal DNS resolver for many of the same reasons the Internet needs public DNS resolvers. In short, humans are good at many things, but remembering long strings of numbers (in this case IP addresses) is not one of them. Both public and internal DNS resolvers were designed to solve this problem (and much more) for us.
In the corporate world, it would be needlessly painful to ask internal users to navigate to, say, 192.168.0.1 to simply reach Sharepoint or OneDrive. Instead, it’s much easier to create DNS entries for each resource and let your internal resolver handle all the mapping for your users as this is something humans are actually quite good at.
Under the hood, DNS queries generally consist of a single UDP request from the client. The server can then return a single reply to the client. Since DNS requests are not very large, they can often be sent and received in a single packet. This makes support for UDP across our Zero Trust platform a key enabler to pulling the plug on your VPN.
Thick Client Applications
Another common use case for UDP is thick client applications. One benefit of UDP we have discussed so far is that it is a lean protocol. It’s lean because the three-way handshake of TCP and other measures for reliability have been stripped out by design. In many cases, application developers still want these reliability controls, but are intimately familiar with their applications and know these controls could be better handled by tailoring them to their application. These thick client applications often perform critical business functions and must be supported end-to-end to migrate. As an example, legacy versions of Outlook may be implemented through thick clients where most of the operations are performed by the local machine, and only the sync interactions with Exchange servers occur over UDP.
Again, UDP support on our Zero Trust platform now means these types of applications are no reason to remain on your legacy VPN.
And more…
A huge portion of the world’s Internet traffic is transported over UDP. Often, people equate time-sensitive applications with UDP, where occasionally dropping packets would be better than waiting — but there are a number of other use cases, and we’re excited to be able to provide sweeping support.
How can I get started today?
You can already get started building your private network on Cloudflare with our tutorials and guides in our developer documentation. Below is the critical path. And if you’re already a customer, and you’re interested in joining the waitlist for UDP and Internal DNS access, please skip ahead to the end of this post!
Connecting your network to Cloudflare
First, you need to install cloudflared on your network and authenticate it with the command below:
cloudflared tunnel login
Next, you’ll create a tunnel with a user-friendly name to identify your network or environment.
cloudflared tunnel create acme-network
Finally, you’ll want to configure your tunnel with the IP/CIDR range of your private network. By doing this, you’re making the Cloudflare WARP agent aware that any requests to this IP range need to be routed to our new tunnel.
cloudflared tunnel route ip add 192.168.0.1/32
Then, all you need to do is run your tunnel!
Connecting your users to your network
To connect your first user, start by downloading the Cloudflare WARP agent on the device they’ll be connecting from, then follow the steps in our installer.
Next, you’ll visit the Teams Dashboard and define who is allowed to access our network by creating an enrollment policy. This policy can be created under Settings > Devices > Device Enrollment. In the example below, you can see that we’re requiring users to be located in Canada and have an email address ending @cloudflare.com.
Once you’ve created this policy, you can enroll your first device by clicking the WARP desktop icon on your machine and navigating to preferences > Account > Login with Teams.
Last, we’ll remove the IP range we added to our Tunnel from the Exclude list in Settings > Network > Split Tunnels. This will ensure this traffic is, in fact, routed to Cloudflare and then sent to our private network Tunnel as intended.
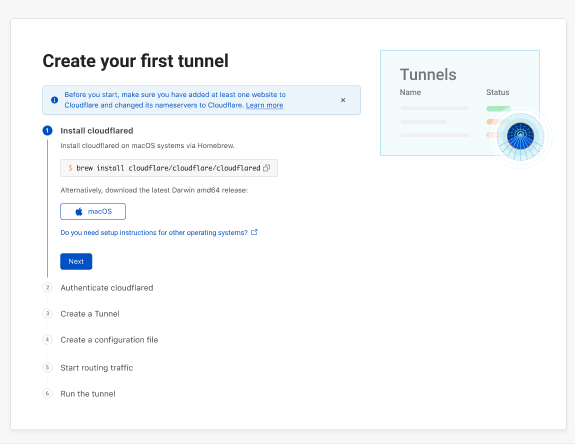
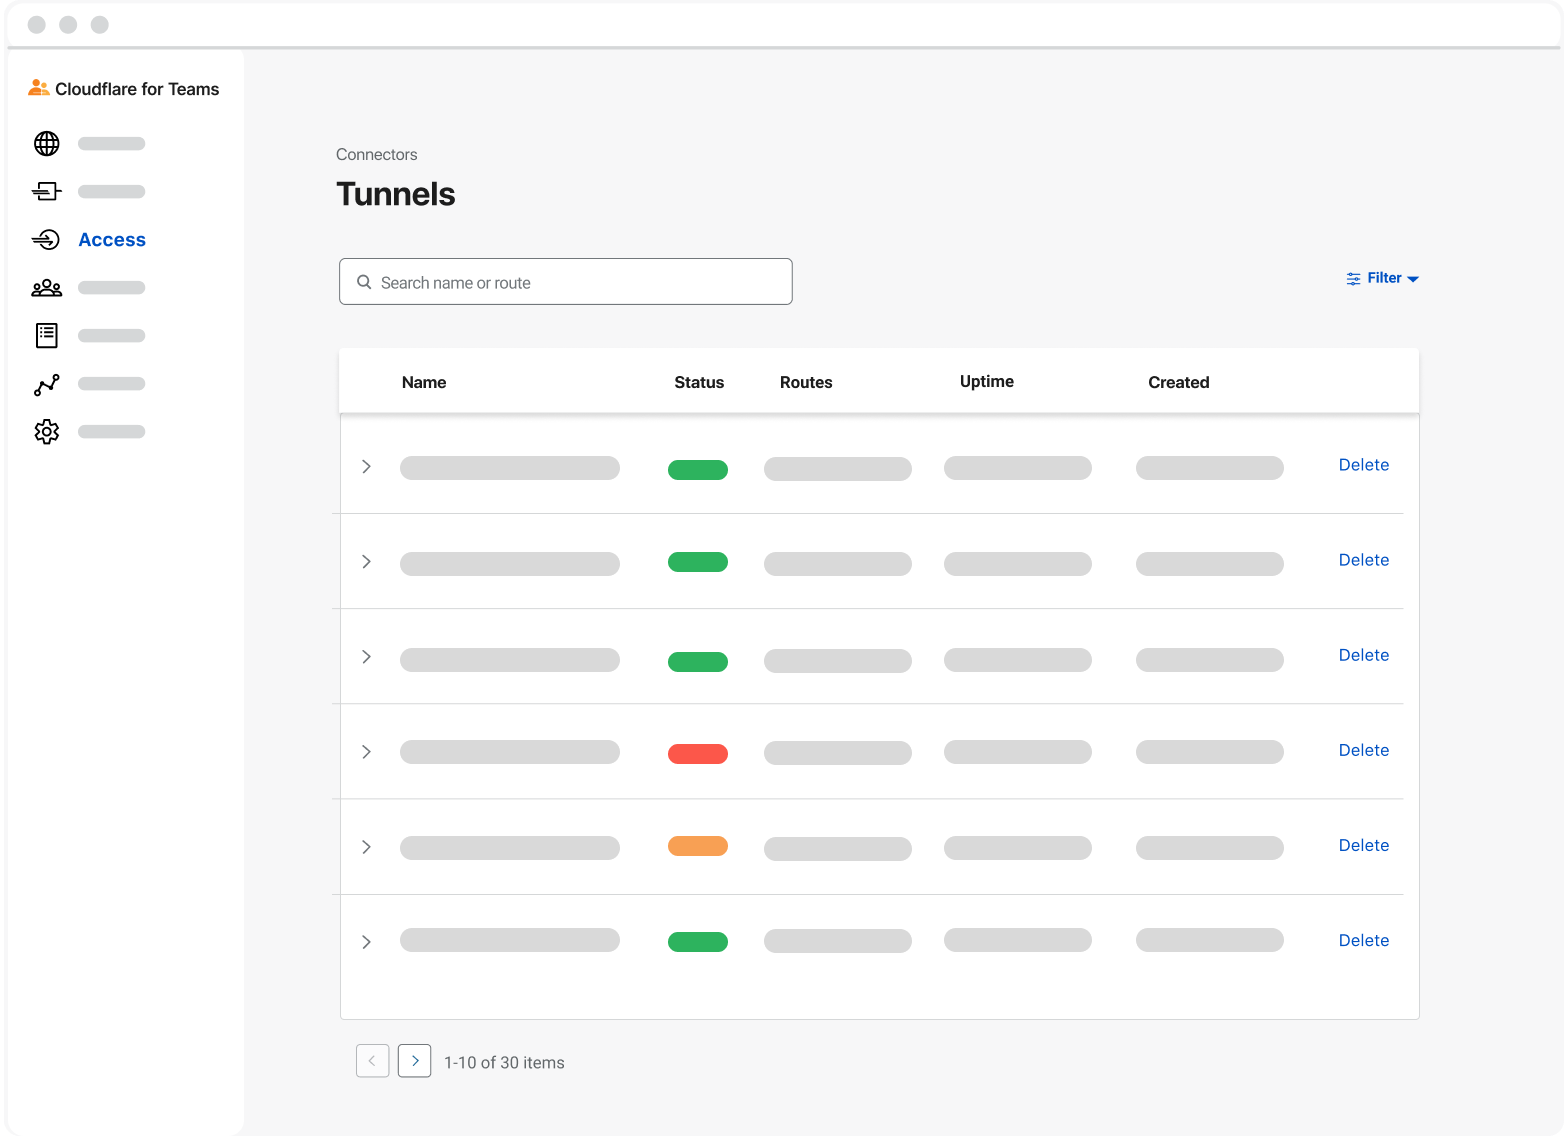
In addition to the tutorial above, we also have in-product guides in the Teams Dashboard which go into more detail about each step and provide validation along the way.
To enroll your first device into WARP, navigate to My Team > Devices.
What’s Next
We’re incredibly excited to release our waitlist today and even more excited to launch this feature in the coming weeks. We’re just getting started with private network Tunnels and plan to continue adding more support for Zero Trust access rules for each request to each internal DNS hostname after launch. We’re also working on a number of efforts to measure performance and to ensure we remain the fastest Zero Trust platform — making using us a delight for your users, compared to the pain of using a legacy VPN.
Supply chain attacks are a growing concern for CIOs and security professionals.
During a supply chain attack, an attacker compromises a third party tool or library that is being used by the target application. This normally results in the attacker gaining privileged access to the application’s environment allowing them to steal private data or perform subsequent attacks. For example, Magecart, is a very common type of supply chain attack, whereby the attacker skimms credit card data from e-commerce site checkout forms by compromising third party libraries used by the site.
To help identify and mitigate supply chain attacks in the context of web applications, today we are launching Page Shield in General Availability (GA).
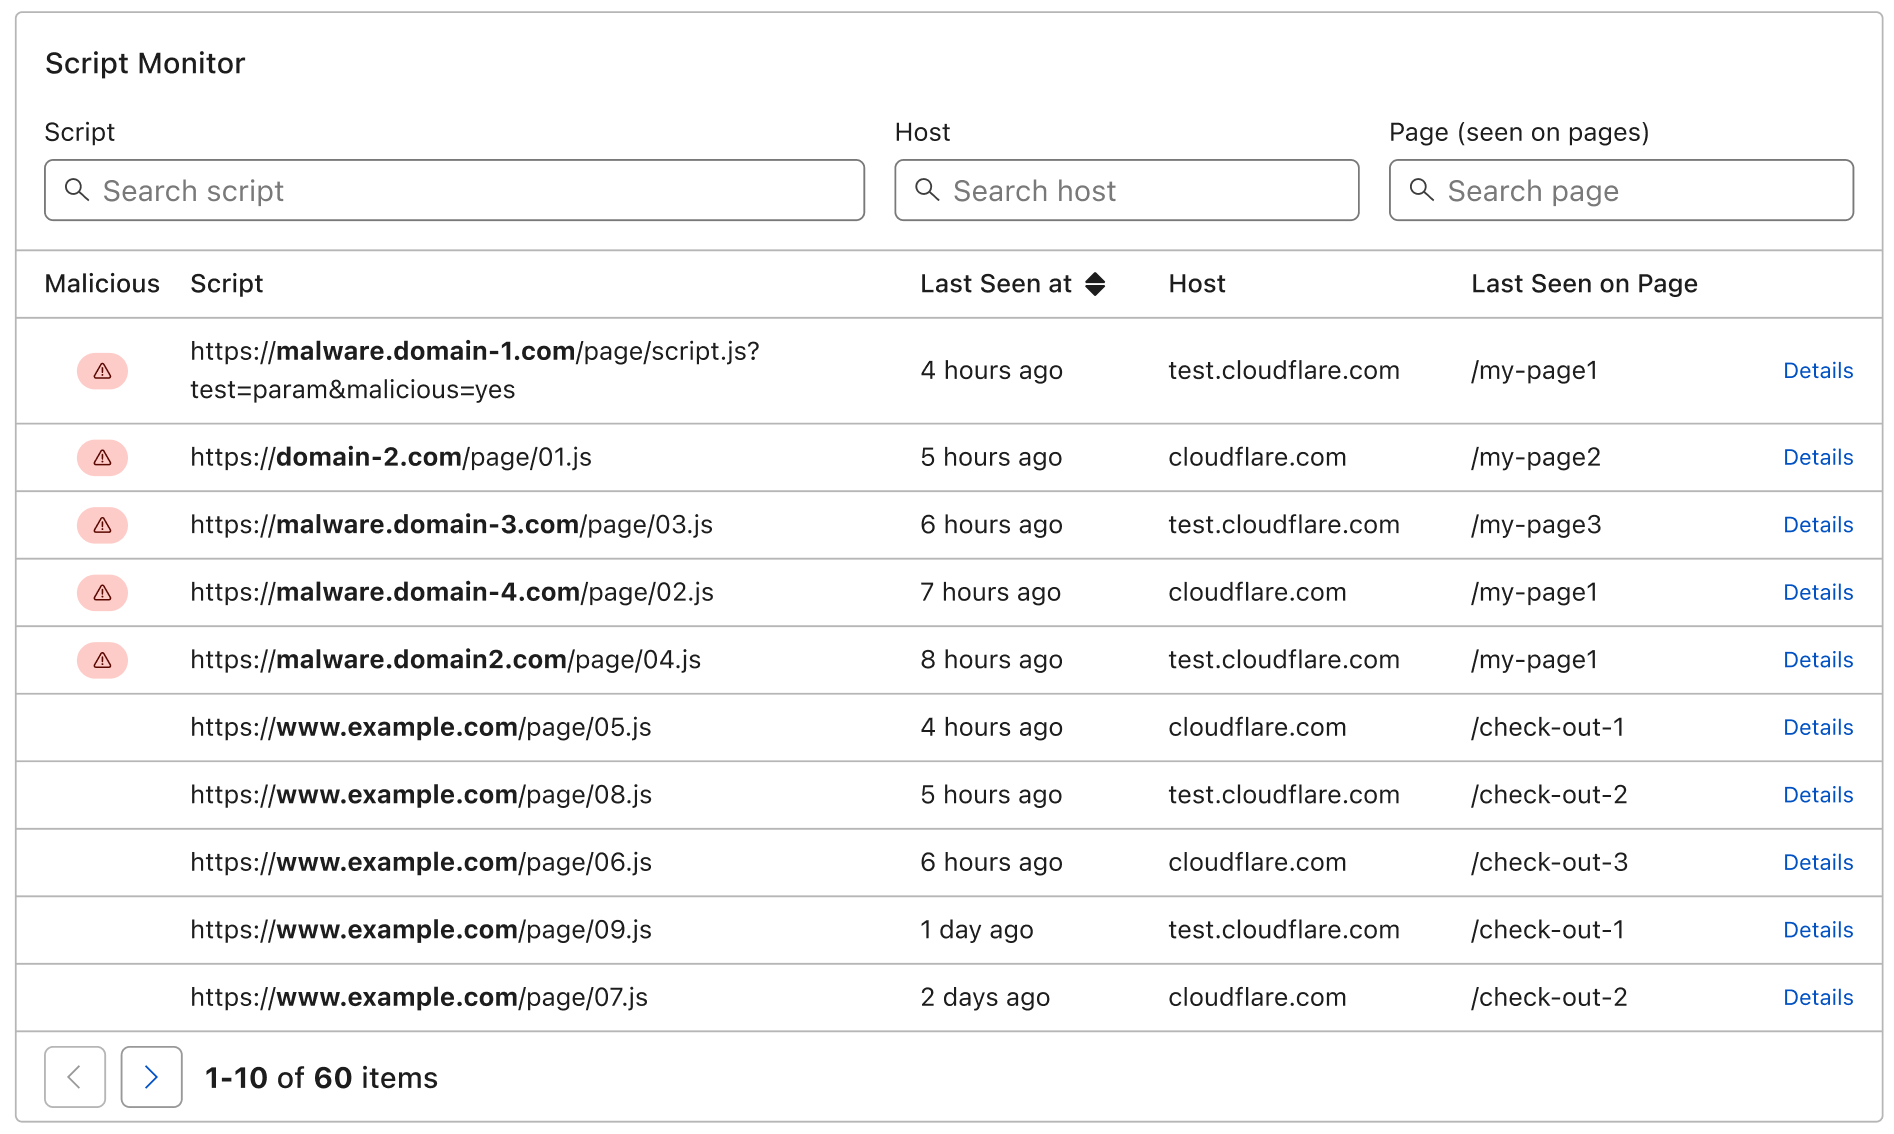
With Page Shield you gain visibility on what scripts are running on your application and can be notified when they have been compromised or are showing malicious behaviour such as attempting to exfiltrate user data.
We’ve worked hard to make Page Shield easy to use: you can find it under the Firewall tab and turn it on with one simple click. No additional configuration required. Alerts can be set up separately on an array of different events.
Earlier today, we announced our acquisition of Zaraz, a tool built on Workers that allows customers to easily load third-party tools on the cloud, instead of loading their JavaScript code in the browser, directly from the Cloudflare UI with immediate performance and security benefits. But not all applications use, or wish to use, a third-party manager. Nonetheless, we have got you covered.
Page Shield leverages our position in the network as a reverse proxy to receive information directly from the browser about what JavaScript files and modules are being loaded. We then provide visibility, analyse, and warn you whenever a JavaScript file is showing malicious behaviour.
Examples of compromised JavaScript files include Magecart attacks, cryptomining, and adware. With the ever-growing popularity of SaaS-based applications and services, it is very rare to find an application that does not leverage or load JavaScript code directly from third parties out of the application owner’s control, making detecting and mitigating compromised files even harder.
How hard is client-side security?
Early indications from Page Shield indicate that, on average, any given application is loading scripts from eight third-party hosts. These hosts could be owned by large enterprises such as Google, to smaller companies that provide “plug and play” modules that quickly enhance web application functionality (think chat systems, date pickers, checkout platforms etc.). Each one of these third parties can be a target for a potential supply chain attack, making the attack surface very large and difficult to monitor.
To make matters worse, things change fast. On average about 50% of applications are loading scripts from new third party hosts every month. This indicates that the attack surface is not only large, but also changing rapidly.
How does Page Shield work?
As with any security product, we can think of Page Shield as providing visibility, detection, mitigation, and prevention. The first step is visibility.
Visibility
When turned on, the current iteration of Page Shield uses a content security policy (CSP) deployed with a report-only directive to collect information from the browser. This allows us to provide you with a list of all scripts running on your application.
In HTTP terms, this is an HTTP response header added to a sample of page responses from the origin server back to the browser. The CSP header looks like this:
The above header instructs the browser that no scripts should be loaded (script-src 'none') and to report any violation to the endpoint provided (report-uri /cdn-cgi/script_monitor/report). Also note that the violation report endpoint resolves to the Cloudflare network where it is processed, so no additional traffic reaches the origin server.
Each violation report sent by the browser, implemented as an HTTP POST request, provides us with information on the script. Here is an example:
The page the script was loaded from (document-uri)
The referrer, if applicable
Which CSP directive was violated
The full CSP that contains the directive
The full link to the JavaScript file
The response code the browser received when loading the file. In the example above, the response code is 200, which indicates that the file was loaded successfully.
By collating all the information provided in the reports and enhancing it with additional data, we are able to provide detailed information on every script being loaded by your application, both via the Cloudflare UI and API.
All Cloudflare Pro zones have access to our Page Shield script reports. Additionally, Business and Enterprise zones have access to page attribution information, allowing you to quickly identify where a script is being loaded from within your application. Business and Enterprise zones can also set up alerts on a number of script change events.
Detection
Application owners might be leveraging content security policies already to ensure only specific scripts are loaded. However, CSPs often tend to be too liberal, and browsers provide no native mechanisms to detect when JavaScript files show malicious behaviour. This includes JavaScript code that is allowed to be loaded according to a content security policy, highly reducing their effectiveness.
With Page Shield we believe to have a real opportunity to help our customers with malicious behaviour detection.
For any JavaScript file found in your zone by the system, we will perform a number of actions aimed at detecting malicious behaviour:
Any JavaScript file loaded from a hostname categorised as malicious in our threat feeds will be flagged appropriately. This includes parent domains.
Similarly, if specific URLs are categorised as malicious in our feeds, these will also be flagged. In this latter case, given the exact file has been categorized as malicious, an attack is likely ongoing.
Finally, we will download the file and run it through our classifier. The classifier performs deobfuscation, normalisation and decoding steps before looking for correlations between form field fetches and data exfiltration calls. The stronger the correlation the more likely the script is performing a Magecart type attack. We will post additional technical details about our technology in follow-up posts — stay tuned!
Our Enterprise customers can purchase the full set of Page Shield capabilities, including the detection capabilities. Please contact your account manager.
As we build the product further through next year, we plan to add additional detection signals as well as improve upon our classifier and detect additional attack types, including adware, ransomware and crypto mining.
Once a malicious signal triggers on a JavaScript file, Cloudflare is able to notify you via an alert that can be set up via email, webhook, PagerDuty, and other formats.
Although not included in this immediate release, we are already hard at work to bring both prevention and mitigation options to Page Shield:
Prevention by allowing easy CSP generation based on observed active scripts, allowing for editing and redeploying of policies as required either via the dashboard or directly via API as part of a deployment pipeline.
Blocking by leveraging our proxy to allow for malicious scripts to be removed inline from HTTP response bodies.
Get started
If you already have a website on Cloudflare, upgrade to any of our paid plans to start leveraging Page Shield features today without any additional configuration required. You can also use our API to leverage Page Shield features.
If you do not have a website on Cloudflare, signing up only takes 5 minutes!
Today, we’re announcing Foundation DNS, Cloudflare’s new premium DNS offering that provides unparalleled reliability, supreme performance and is able to meet the most complex requirements of infrastructure teams.
Let’s talk money first
When you’re signing an enterprise DNS deal, usually DNS providers request three inputs from you in order to generate a quote:
Number of zones
Total DNS queries per month
Total DNS records across all zones
Some are considerably more complicated and many have pricing calculators or opaque “Contact Us” pricing. Planning a budget around how you may grow brings unnecessary complexity, and we think we can do better. Why not make this even simpler? Here you go: We decided to charge Foundation DNS based on a single input for our enterprise customers: Total DNS queries per month.This way, we expect to save companies money and even more importantly, remove complexity from their DNS bill.
And don’t worry, just like the rest of our products, DDoS mitigation is still unmetered. There won’t be any hidden overage fees in case your nameservers are DDoS’d or the number of DNS queries exceeds your quota for a month or two.
Why is DNS so important?
The Domain Name System (DNS) is nearly as old as the Internet itself. It was originally defined in RFC882 and RFC883 in 1983 out of the need to create a mapping between hostnames and IP addresses. Back then, the authors wisely stated: “[The Internet] is a large system and is likely to grow much larger.” [RFC882]. Today there are almost 160 Million domain names just under the .com, one of the largest Top Level Domains (TLD) [source].
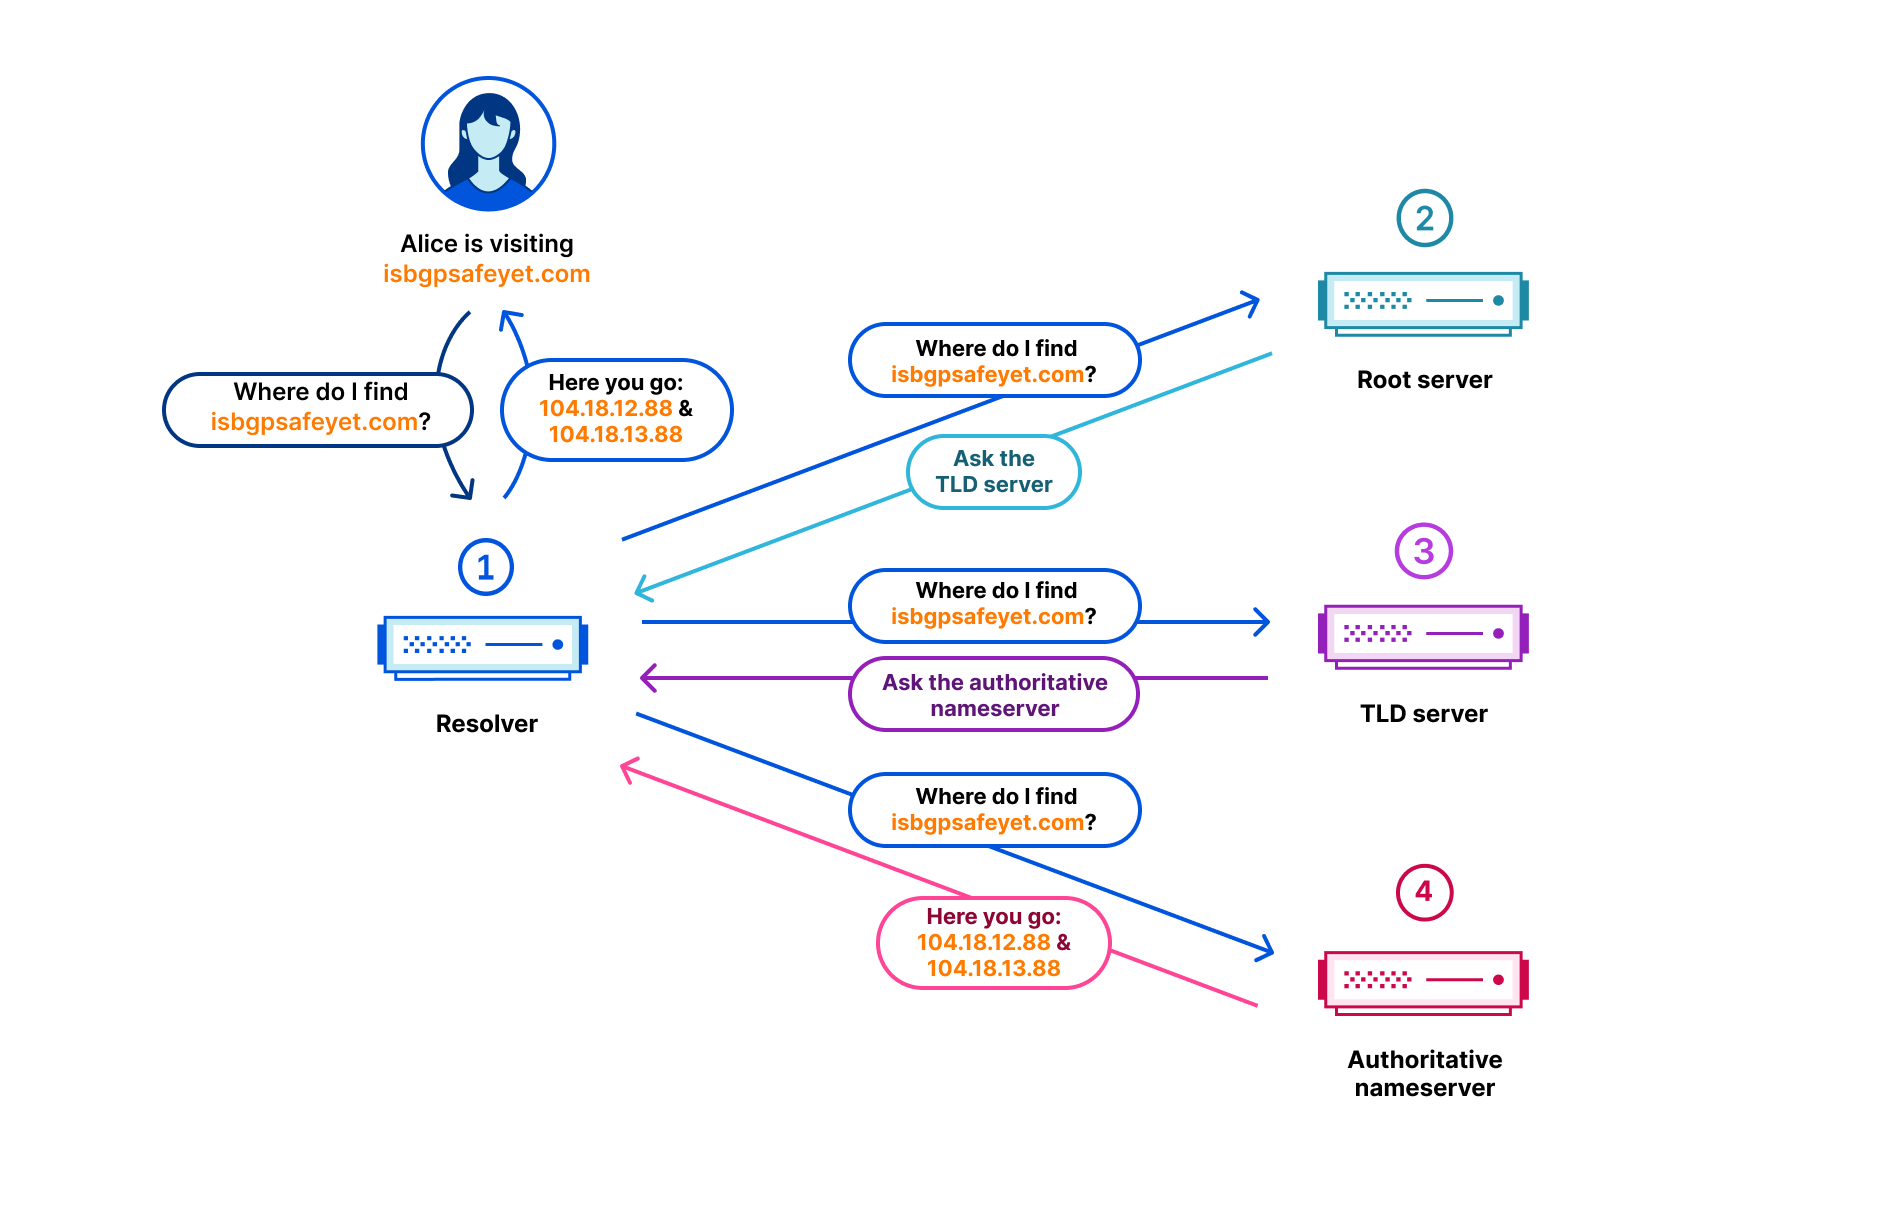
By design, DNS is a hierarchical and highly distributed system, but as an end user you usually only communicate with a resolver (1) that is either assigned or operated by your Internet Service Provider (ISP) or directly configured by your employer or yourself. The resolver communicates with one of the root servers (2), the responsible TLD server (3) and the authoritative nameserver (4) of the domain in question. In many cases all of these four parties are operated by a different entity and located in different regions, maybe even continents.
As we have seen in the recent past, if your DNS infrastructure goes down you are in serious trouble, and it likely will cost you a lot of money and potentially damage your reputation. So as a domain owner you want that DNS lookups to your domain are answered 100% of the time and ideally as quickly as possible. So what can you do? You cannot influence which resolver your users have configured. You cannot influence the root server. You can choose which TLD server is involved by picking a domain name with the respective TLD. But if you are bound to a certain TLD for other reasons then that is out of your control as well. What you can easily influence is the provider for your authoritative nameservers. So let’s take a closer look at Cloudflare’s authoritative DNS offering.
A look at Cloudflare’s Authoritative DNS
Authoritative DNS is one of our oldest products, and we have spent a lot of time making it great. All DNS queries are answered from our global anycast network with a presence in more than 250 cities. This way we can deliver supreme performance while always guaranteeing global availability. And of course, we leverage our extensive experience in mitigating DDoS attacks to prevent anyone from knocking down our nameservers and with that the domains of our customers.
DNS is critically important to Cloudflare because up until the release of Magic Transit, DNS was how every user on the Internet was directed to Cloudflare to protect and accelerate our customer’s applications. If our DNS answers were slow, Cloudflare was slow. If our DNS answers were unavailable, Cloudflare was unavailable. Speed and reliability of our authoritative DNS is paramount to the speed and reliability of Cloudflare, as it is to our customers. We have also had our customers push our DNS infrastructure as they’ve grown with Cloudflare. Today our largest customer zone has more than 3 million records and the top 5 are reaching almost 10 million records combined. Those customers rely on Cloudflare to push new DNS record updates to our edge in seconds, not minutes. Due to this importance and our customer’s needs, over the years we have grown our dedicated DNS engineering team focused on keeping our DNS stack fast and reliable.
The security of the DNS ecosystem is also important. Cloudflare has always been a proponent of DNSSEC. Signing and validating DNS answers through DNSSEC ensures that an on-path attacker cannot hijack answers and redirect traffic. Cloudflare has always offered DNSSEC for free on all plan levels, and it will continue to be a no charge option for Foundation DNS. For customers who also choose to use Cloudflare as a registrar, simple one-click deployment of DNSSEC is another key feature that ensures our customers’ domains are not hijacked, and their users are protected. We support RFC 8078 for one-click deployment on external registrars as well.
But there are other issues that can bring parts of the Internet to a halt and these are mostly out of our control: route leaks or even worse route hijacking. While DNSSEC can help with mitigating route hijacks, unfortunately not all recursive resolvers will validate DNSSEC. And even if the resolver does validate, a route leak or hijack to your nameservers will still result in downtime. If all your nameserver IPs are affected by such an event, your domain becomes unresolvable.
With many providers each of your nameservers usually resolves to only one IPv4 and one IPv6 address. If that IP address is not reachable — for example because of network congestion or, even worse, a route leak — the entire nameserver becomes unavailable leading to your domain becoming unresolvable. Even worse, some providers even use the same IP subnet for all their nameservers. So if there is an issue with that subnet all nameservers are down.
All nameserver IPs are part of 205.251.192.0/21. Thankfully, AWS is now signing their ranges through RPKI and this makes it less likely to leak… provided that the resolver ISP is validating RPKI. But if the resolver ISP does not validate RPKI and should this subnet be leaked or hijacked, resolvers wouldn’t be able to reach any of the nameservers and aws.com would become unresolvable.
It goes without saying that Cloudflare signs all of our routes and are pushing the rest of the Internet to minimize the impact of route leaks, but what else can we do to ensure that our DNS systems remain resilient through route leaks while we wait for RPKI to be ubiquitously deployed?
Today, when you’re using Cloudflare DNS on the Free, Pro, Business or Enterprise plan, your domain gets two nameservers of the structure <name>.ns.cloudflare.com where <name> is a random first name.
Now, as we learned before, in order for a domain to be available, its nameservers have to be available. This is why each of these nameservers resolves to 3 anycast IPv4 and 3 anycast IPv6 addresses.
The essential detail to notice here is that each of the 3 IPv4 and 3 IPv6 addresses is from a different /8 IPv4 (/45 for IPv6) block. So in order for your nameservers to become unavailable via IPv4, the route leak would have to affect exactly the corresponding subnets across all three /8 IPv4 blocks. This type of event, while theoretically is possible, is virtually impossible in practical terms.
How can this be further improved?
Customers using Foundation DNS will be assigned a new set of advanced nameservers hosted on foundationdns.com and foundationdns.net. These nameservers will be even more resilient than the default Cloudflare nameservers. We will be announcing more details about how we’re achieving this early next year, so stay tuned. All external Cloudflare domains (such as cloudflare.com) will transition to these nameservers in the new year.
There is even more
We’re glad to announce that we are launching two highly requested features:
Support for outgoing zone transfers for Secondary DNS
Logpush for authoritative and secondary DNS queries
Both of them will be available as part of Foundation DNS and to enterprise customers without any additional costs. Let’s take a closer look at each of these and see how they make our DNS offering even better.
Support for outgoing zone transfers for Secondary DNS
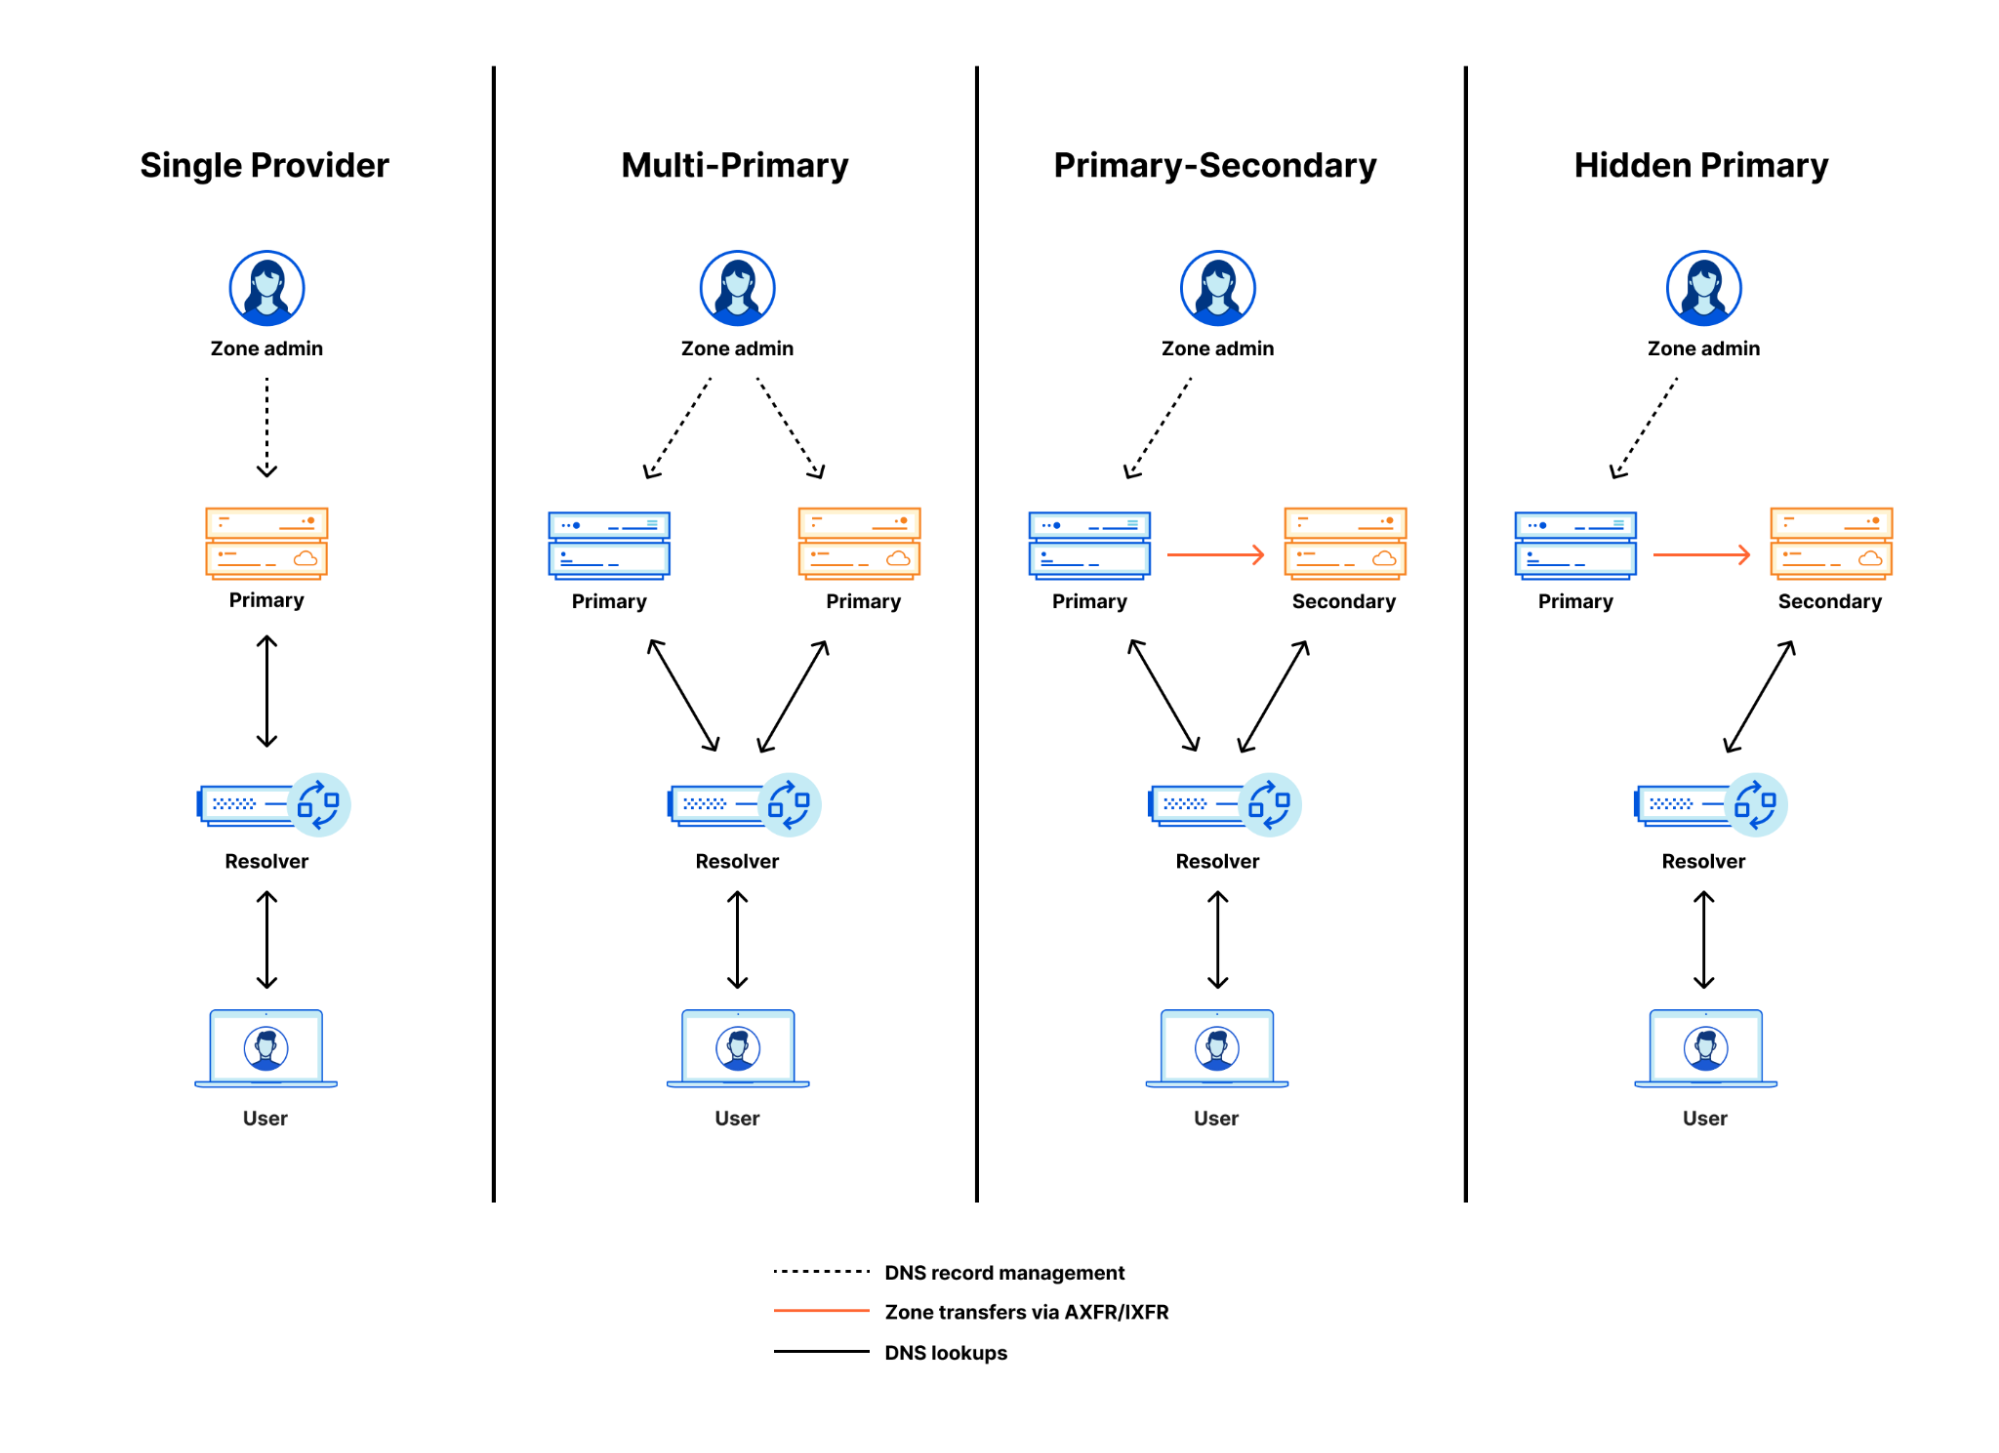
What is Secondary DNS, and why is it important? Many large enterprises have requirements to use more than one DNS provider for redundancy in case one provider becomes unavailable. They can achieve this by adding their domain’s DNS records on two independent platforms and manually keeping the zone files in sync — this is referred to as “multi-primary” setup. With Secondary DNS there are two mechanisms how this can be automated using a “primary-secondary” setup:
DNS NOTIFY: The primary nameserver notifies the secondary on every change on the zone. Once the secondary receives the NOTIFY, it sends a zone transfer request to the primary to get in sync with it.
SOA query: Here, the secondary nameserver regularly queries the SOA record of the zone and checks if the serial number that can be found on the SOA record is the same with the latest serial number the secondary has stored in it’s SOA record of the zone. If there is a new version of the zone available, it sends a zone transfer request to the primary to get those changes.
Alex Fattouche has written a very insightful blog post about how Secondary DNS works behind the scenes if you want to learn more about it. Another flavor of the primary-secondary setup is to hide the primary, thus referred to as “hidden primary”. The difference of this setup is that only the secondary nameservers are authoritative — in other words configured at the domain’s registrar. The diagram below illustrates the different setups.
Since 2018, we have been supporting primary-secondary setups where Cloudflare takes the role of the secondary nameserver. This means from our perspective that we are accepting incoming zone transfers from the primary nameservers.
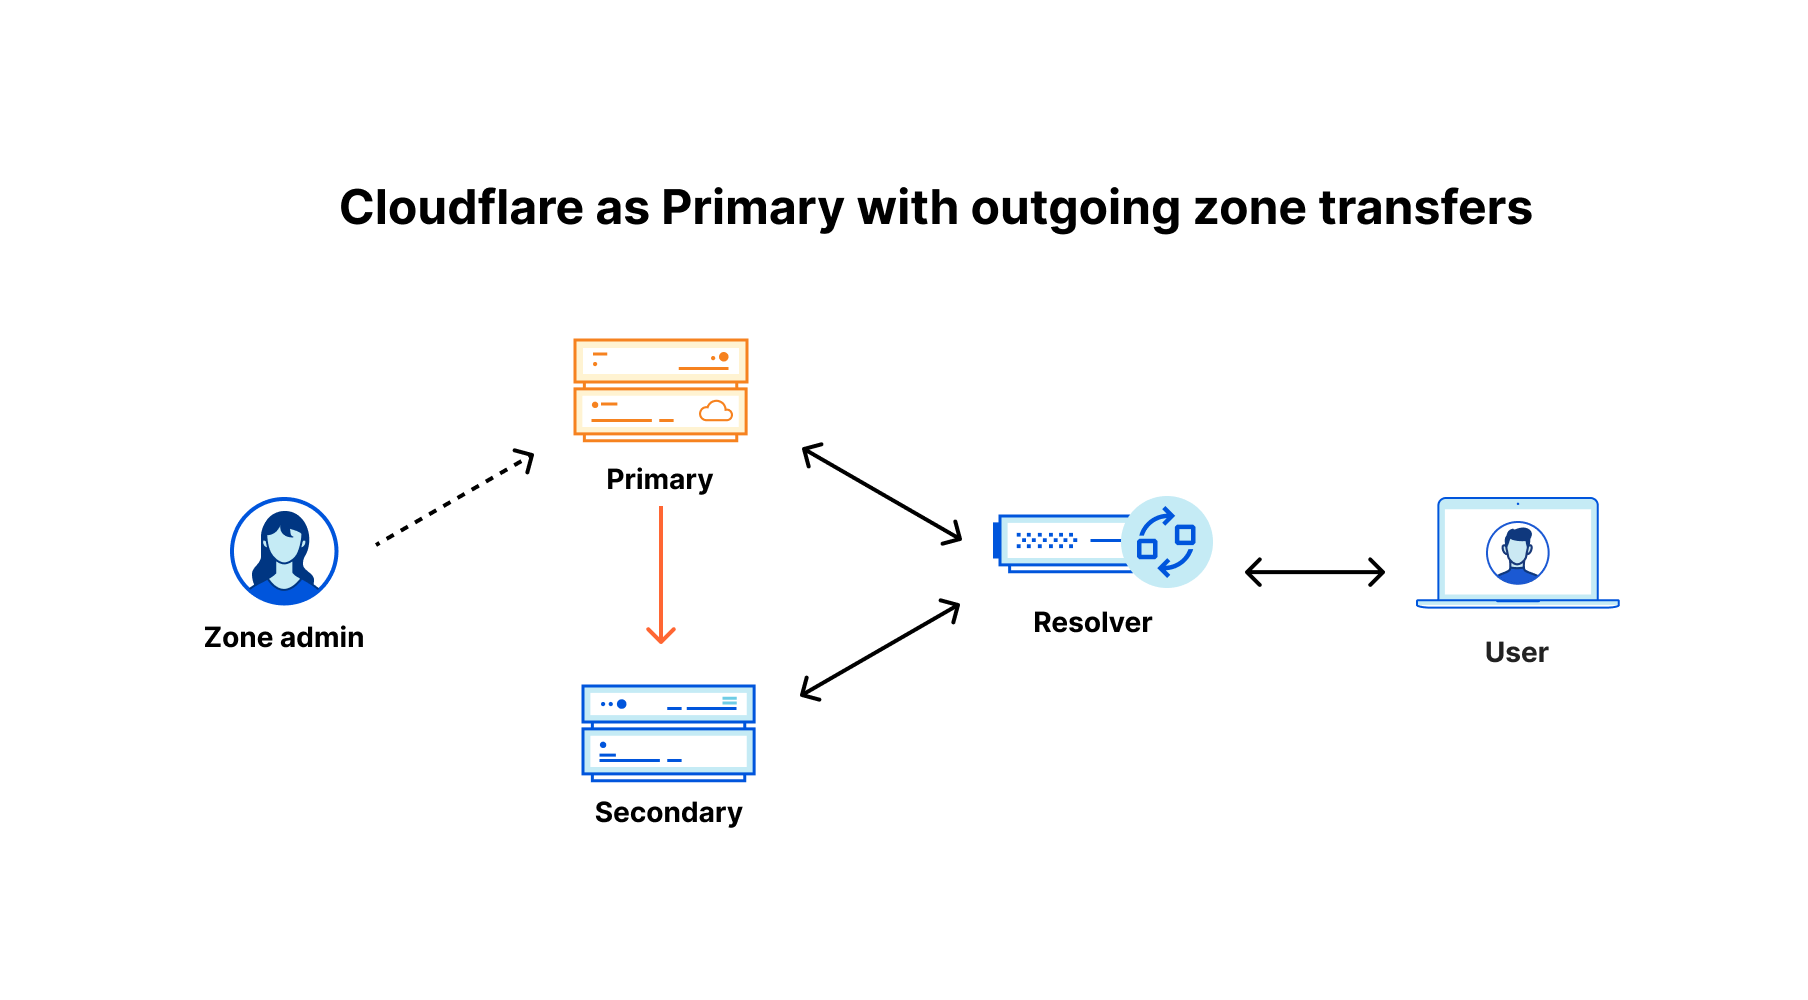
Starting today, we are now also supporting outgoing zone transfers, meaning taking the role of the primary nameserver with one or multiple external secondary nameservers receiving zone transfers from Cloudflare. Exactly as for incoming transfers, we are supporting
zone transfers via AXFR and IXFR
automatic notifications via DNS NOTIFY to trigger zone transfers on every change
signed transfers using TSIG to ensure zone files are authenticated during transfer
Logpush for authoritative and secondary DNS
Here at Cloudflare we love logs. In Q3 2021, we processed 28 Million HTTP requests per second and 13.6 Million DNS queries per second on average and blocked 76 Billion threats each day. All these events are stored as logs for a limited time frame in order to provide our users near real-time analytics in the dashboard. For those customers who want to — or have to — permanently store these logs we’ve built Logpush back in 2019. Logpush allows you to stream logs in near real time to one of our analytics partners Microsoft Azure Sentinel, Splunk, Datadog and Sumo Logic or to any cloud storage destination with R2-compatible API.
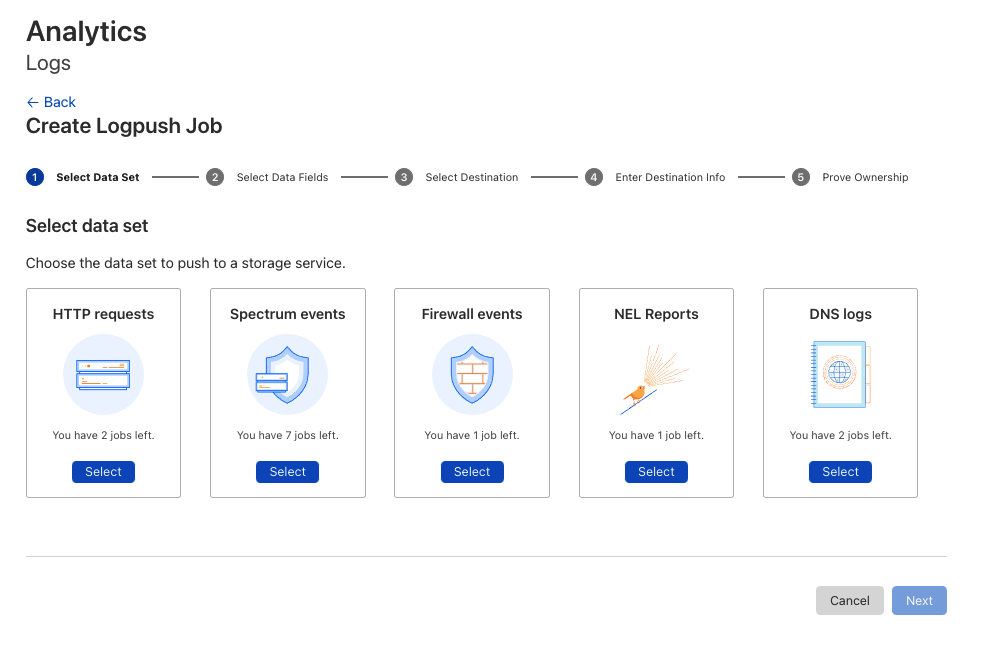
Today, we’re adding one additional data set for Logpush: DNS logs. In order to configure Logpush and stream DNS logs for your domain, just head over to the Cloudflare dashboard, create a new Logpush job, select DNS logs and configure the log fields you’re interested in:
Check out our developer documentation for detailed instructions on how to do this through the API and for a thorough description of the new DNS log fields.
One more thing (or two…)
When looking at the entirety of DNS within your infrastructure, it’s important to review how your traffic is flowing through your systems and how that traffic is behaving. At the end of the day, there is only so much processing power, memory, server capacity, and overall compute resources available. One of the best and important tools we have available is Load Balancing and Health Monitoring!
Cloudflare has provided a Load Balancing solution since 2016, supporting customers to leverage their existing resources in a scalable and intelligent manner. But our Load Balancer was limited to A, AAAA, and CNAME records. This covered a lot of major use cases required by customers, but did not cover all of them. Many customers have more needs such as load balancing MX or email server traffic, SRV records to declare which ports and weight that respective traffic should travel across for a specific service, HTTPS records to ensure the respective traffic uses the secure protocol regardless of port and many more. We want to ensure that our customers’ needs are covered and support their ability to align business goals with technical implementation.
We are happy to announce that we have added additional Health Monitoring methods to support Load Balancing MX, SRV, HTTPS and TXT record traffic without any additional configuration necessary. Create your respective DNS records in Cloudflare and set your Load Balancer as the destination…it’s as easy as that! By leveraging ICMP Ping, SMTP, and UDP-ICMP methods, customers will always have a pulse on the health of their servers and be able to apply intelligent steering decisions based on the respective health information.
When thinking about intelligent steering, there is no one size fits all answer. Different businesses have different needs, especially when looking at where your servers are located around the globe, and where your customers are situated. A common rule of thumb to follow is to place servers where your customers are. This ensures they have the most performant and localized experience possible. One common scenario is to steer your traffic based on where your end-user request originates and create a mapping to the server closest to that area. Cloudflare’s geo steering capability allows our customers to do just that — easily create a mapping of regions to pools, ensuring if we see a request originate from Eastern Europe, to send that request to the proper server to suffice that request. But sometimes, regions can be quite large and lend to issues around not being able to tightly couple together that mapping as closely as one might like.
Today, we are very excited to announce country support within our Geo Steering functionality. Now, customers will be able to choose either one of our thirteen regions, or a specific country to map against their pools to give further granularity and control to how customers traffic should behave as it travels through their system. Both country-level steering and our new health monitoring methods to support load balancing more DNS records will be available in January 2022!
Advancing the DNS Ecosystem
Furthermore, we have some other exciting news to share: We’re finishing the work on Multi-Signer DNSSEC (RFC8901) and plan to roll this out in Q1 2022. Why is this important? Two common requirements of large enterprises are:
Redundancy: Having multiple DNS providers responding authoritatively for their domains
Authenticity: Deploying DNSSEC to ensure DNS responses can be properly authenticated
Both can be achieved by having the primary nameserver sign the domain and transfer its DNS records plus the record signatures to the secondary nameserver which will serve both as is. This setup is supported with Cloudflare Secondary DNS today. What cannot be supported when transferring pre-signed zones are non-standard DNS features like country-level steering. This is where Multi-Signer DNSSEC comes in. Both DNS providers need to know the signing keys of the other provider and perform their own online (or on-the-fly) signing. If you’re curious to learn more about how Multi-Signer DNSSEC works, go check out this excellent blog post published by APNIC.
Last but not least, Cloudflare is joining the DNS Operations, Analysis, and Research Center (DNS-OARC) as a gold member. Together with other researchers and operators of DNS infrastructure we want to tackle the most challenging problems and continuously work on implementing new standards and features.
While we’ve been at DNS since day one of Cloudflare, we’re still just getting started. We know there are more granular and specific features our future customers will ask of us and the launch of Foundation DNS is our stake in the ground that we will continue to invest in all levels of DNS while building the most feature rich enterprise DNS platform on the planet. If you have ideas, let us know what you’ve always dreamed your DNS provider would do. If you want to help build these features, we are hiring.
We’re excited to announce that customers will soon be able to store their Cloudflare logs on Cloudflare R2 storage. Storing your logs on Cloudflare will give CIOs and Security Teams an opportunity to consolidate their infrastructure; creating simplicity, savings and additional security.
Cloudflare protects your applications from malicious traffic, speeds up connections, and keeps bad actors out of your network. The logs we produce from our products help customers answer questions like:
Why are requests being blocked by the Firewall rules I’ve set up?
Why are my users seeing disconnects from my applications that use Spectrum?
Why am I seeing a spike in Cloudflare Gateway requests to a specific application?
Storage on R2 adds to our existing suite of logging products. Storing logs on R2 fills in gaps that our customers have been asking for: a cost-effective solution to store logs for any of our products for any period of time.
Goodbye to old school logging
Let’s rewind to the early 2000s. Most organizations were running their own self-managed infrastructure: network devices, firewalls, servers and all the associated software. Each company has to manage logs coming from hundreds of sources in the IT stack. With dedicated storage needed for retaining an endless volume of logs, specialized teams are required to build an ETL pipeline and make the data actionable.
Fast-forward to the 2010s. Organizations are transitioning to using managed services for their IT functions. As a result of this shift, the way that customers collect logs for all their services have changed too. With managed services, much of the logging load is shifted off of the customer.
The challenge now: collecting logs from a combination of managed services, each of which has its own quirks. Logs can be sent at varying latencies, in different formats and some are too detailed while others not detailed enough. To gain a single pane view of their IT infrastructure, companies need to build or buy a SIEM solution.
Cloudflare replaces these sets of managed services. When a customer onboards to Cloudflare, we make it super easy to gain visibility to their traffic that hits our network. We’ve built analytics for many of our products, such as CDN, Firewall, Magic Transit and Spectrum to both view high level trends and dig into patterns by slicing and dicing data.
Analytics are a great way to see data at an aggregate level, but we know that raw logs are important to our customers as well, so we’ve built out a set of logging products.
Logging today
During Speed Week we announced Instant Logs to show customers traffic as it hits their domain. Instant Logs is perfect for live debugging and triaging use cases. Monitor your traffic, make a config change and instantly view its impacts. In cases where you need to retroactively inspect your logs, we have Logpush.
We’ve built an impressive logging pipeline to get data from the 250+ cities that house our data centers to our customers in under a minute using Logpush. If your organization has existing practices for getting data across your stack into one place, we support Logpush to a variety of cloud storage or SIEM destinations. We also have partnerships in place with major SIEM platforms to surface Cloudflare data in ways that are meaningful to our customers.
Last but not least is Logpull. Using Logpull, customers can access HTTP request logs using our REST API. Our customers like Logpull because it’s easy to configure, they don’t have to worry about storing logs on a third party, and you can pull data ad hoc for up to seven days.
Why Cloudflare storage?
The top four requests we’ve heard from customers when it comes to logs are:
I have tight budgets and need low cost log storage.
They should be low effort to set up and maintain.
I should be able to store logs for as long as I need to.
I want to access my logs on Cloudflare for any product.
For many of our customers, Cloudflare is one of the most important data sources, and it also generates more data than other applications on their IT stack. R2 is significantly cheaper than other cloud providers, so our customers don’t need to compromise by sampling or leaving out logs from products all together in order to cut down on costs.
Just like the simplicity of Logpull, log storage on R2 will be quick and easy. With a one click setup, we’ll store your logs, and you don’t have to worry about any configuration details. Retention is totally in our customer’s control to match the security and compliance needs of their business. With R2, you can also store your logs for any products we have logging for today (and we’re always adding more as our product line expands).
Log storage; we’re just getting started
With log storage on Cloudflare, we’re creating the building blocks to allow customers to perform log analysis and forensics capabilities directly on Cloudflare. Whether conducting an investigation, responding to a support request or addressing an incident, using analytics for a birds eye view and inspecting logs to determine the root cause is a powerful combination.
If you’re interested in getting notified when you can store your logs on Cloudflare, sign up through this form.
We’re always looking for talented engineers to take on the challenges of working with data at an incredible scale. If you’re interested apply here.
Your team can now use Cloudflare’s Browser Isolation service to protect against phishing attacks and credential theft inside the web browser. Users can browse more of the Internet without taking on the risk. Administrators can define Zero Trust policies to prohibit keyboard input and transmitting files during high risk browsing activity.
Earlier this year, Cloudflare Browser Isolation introduced data protection controls that take advantage of the remote browser’s ability to manage all input and outputs between a user and any website. We’re excited to extend that functionality to apply more controls such as prohibiting keyboard input and file uploads to avert phishing attacks and credential theft on high risk and unknown websites.
Challenges defending against unknown threats
Administrators protecting their teams from threats on the open Internet typically implement a Secure Web Gateway (SWG) to filter Internet traffic based on threat intelligence feeds. This is effective at mitigating known threats. In reality, not all websites fit neatly into malicious or non-malicious categories.
For example, a parked domain with typo differences to an established web property could be legitimately registered for an unrelated product or become weaponized as a phishing attack. False-positives are tolerated by risk-averse administrators but come at the cost of employee productivity. Finding the balance between these needs is a fine art, and when applied too aggressively it leads to user frustration and the increased support burden of micromanaging exceptions for blocked traffic.
Legacy secure web gateways are blunt instruments that provide security teams limited options to protect their teams from threats on the Internet. Simply allowing or blocking websites is not enough, and modern security teams need more sophisticated tools to fully protect their teams without compromising on productivity.
Intelligent filtering with Cloudflare Gateway
Cloudflare Gateway provides a secure web gateway to customers wherever their users work. Administrators can build rules that include blocking security risks, scanning for viruses, or restricting browsing based on SSO group identity among other options. User traffic leaves their device and arrives at a Cloudflare data center close to them, providing security and logging without slowing them down.
Unlike the blunt instruments of the past, Cloudflare Gateway applies security policies based on the unique magnitude of data Cloudflare’s network processes. For example, Cloudflare sees just over one trillion DNS queries every day. We use that data to build a comprehensive model of what “good” DNS queries look like — and which DNS queries are anomalous and could represent DNS tunneling for data exfiltration, for example. We use our network to build more intelligent filtering and reduce false positives. You can review that research as well with Cloudflare Radar.
However, we know some customers want to allow users to navigate to destinations in a sort of “neutral” zone. Domains that are newly registered, or newly seen by DNS resolvers, can be the home of a great new service for your team or a surprise attack to steal credentials. Cloudflare works to categorize these as soon as possible, but in those initial minutes users have to request exceptions if your team blocks these categories outright.
Safely browsing the unknown
Cloudflare Browser Isolation shifts the risk of executing untrusted or malicious website code from the user’s endpoint to a remote browser hosted in a low-latency data center. Rather than aggressively blocking unknown websites, and potentially impacting employee productivity, Cloudflare Browser Isolation provides administrators control over how users can interact with risky websites.
Cloudflare’s network intelligence tracks higher risk Internet properties such as Typosquatting and New Domains. Websites in these categories could be benign websites, or phishing attacks waiting to be weaponized. Risk-averse administrators can protect their teams without introducing false-positives by isolating these websites and serving the website in a read-only mode by disabling file uploads, downloads and keyboard input.
Users are able to safely browse the unknown website without risk of leaking credentials, transmitting files and falling victim to a phishing attack. Should the user have a legitimate reason to interact with an unknown website they are advised to contact their administrator to obtain elevated permissions while browsing the website.
Cloudflare Browser Isolation is integrated natively into Cloudflare’s Secure Web Gateway and Zero Trust Network Access services, and unlike legacy remote browser isolation solutions does not require IT teams to piece together multiple disparate solutions or force users to change their preferred web browser.
The Zero Trust threat and data protection that Browser Isolation provides make it a natural extension for any company trusting a secure web gateway to protect their business. We’re currently including it with our Cloudflare for Teams Enterprise Plan at no additional charge.1Get started at our Zero Trust web page.
Cloudflare Radar launched as part of last year’s Birthday Week. We described it as a“newspaper for the Internet”, that gives“any digital citizen the chance to see what’s happening online [which] is part of our pursuit to help build a better, more informed, Internet”.
Since then, we have made considerable strides, including adding dedicated pages to cover how key events such as the UEFA Euro 2020 Championship and the Tokyo Olympics shaped Internet usage in participating countries, and added a Radar section for interactive deep-dive reports on topics such as DDoS.
Today, Radar has four main sections:
Main page with near real-time information about global Internet usage.
Internet usage details by country (see, for example, Portugal).
Domain insights, where searching for a domain returns traffic, registration and certificate information about it.
Deep-dive reports on complex and often underreported topics.
Cloudflare’s global network spans more than 250 cities in over 100 countries. Because of this, we have the unique ability to see both macro and micro trends happening online, including insights on how traffic is flowing around the world or what type of attacks are prevalent in a certain country.
Radar Maps will make this information even richer and easier to consume.
Introducing Radar Maps
Starting today, Radar has two new data visualizations to help us share more insights from our data and represent what’s happening on the Internet.
Geographical distribution of application-level attacks
Note: The identified location of the devices involved in the attack may not be the actual location of the people performing the attack.
Geographical distribution of application-level attacks, in both directions
Cyber threats are more common than ever. In the third quarter of 2021 Cloudflare blocked an average of 76 billion cyber threats each day and had visibility over many more. Helping build a better Internet also means giving people more visibility over our data. That’s why we’ve made a near real-time view of the types of attacks, protocol distribution, and attack volume over time available on Radar from day one.
Now we’re adding a geographical representation of origin and target of such attacks using two new visualizations.
First, we have a global map drawing near real-time directional lines of the attacks, also known as a “pew pew” map — thank you, 1983 and WarGames.
Second, we have Sankey diagrams that are great for representing how strongly the attacks are flowing from one country to the other.
We hope you like what we’ve built with our new Radar Maps. Radar, unlike any other insights platform out there, is totally built on Cloudflare components and our edge computing platform — Workers and Workers KV. This gives us new and unique ways of representing data at scale. So do keep checking back radar.cloudflare.com to see the Internet evolving in (near) real-time.
Until today, Cloudflare Workers has been a great solution to setting headers, but we wanted to create an even smoother developer experience. Today, we’re excited to announce that Pages now natively supports custom headers on your projects! Simply create a _headers file in the build directory of your project and within it, define the rules you want to apply.
/developer-docs/*
  X-Hiring: Looking for a job? We're hiring engineers
(https://www.cloudflare.com/careers/jobs)
What can you set with custom headers?
Being able to set custom headers is useful for a variety of reasons — let’s explore some of your most popular use cases.
Search Engine Optimization (SEO)
When you create a Pages project, a pages.dev deployment is created for your project which enables you to get started immediately and easily preview changes as you iterate. However, we realize this poses an issue — publishing multiple copies of your website can harm your rankings in search engine results. One way to solve this is by disabling indexing on all pages.dev subdomains, but we see many using their pages.dev subdomain as their primary domain. With today’s announcement you can attach headers such as X-Robots-Tag to hint to Google and other search engines how you’d like your deployment to be indexed.
For example, to prevent your pages.dev deployment from being indexed, you can add the following to your _headers file:
Customizing headers doesn’t just help with your site’s search result ranking — a number of browser security features can be configured with headers. A few headers that can enhance your site’s security are:
X-Frame-Options: You can prevent click-jacking by informing browsers not to embed your application inside another (e.g. with an <iframe>).
X-Content-Type-Option: nosniff: To prevent browsers from interpreting a response as any other content-type than what is defined with the Content-Type header.
Referrer-Policy: This allows you to customize how much information visitors give about where they’re coming from when they navigate away from your page.
Permissions-Policy: Browser features can be disabled to varying degrees with this header (recently renamed from Feature-Policy).
Content-Security-Policy: And if you need fine-grained control over the content in your application, this header allows you to configure a number of security settings, including similar controls to the X-Frame-Options header.
You can configure these headers to protect an /app/* path, with the following in your _headers file:
Modern browsers implement a security protection called CORS or Cross-Origin Resource Sharing. This prevents one domain from being able to force a user’s action on another. Without CORS, a malicious site owner might be able to do things like make requests to unsuspecting visitors’ banks and initiate a transfer on their behalf. However, with CORS, requests are prevented from one origin to another to stop the malicious activity.
There are, however, some cases where it is safe to allow these cross-origin requests. So-called, “simple requests” (such as linking to an image hosted on a different domain) are permitted by the browser. Fetching these resources dynamically is often where the difficulty arises, and the browser is sometimes overzealous in its protection. Simple static assets on Pages are safe to serve to any domain, since the request takes no action and there is no visitor session. Because of this, a domain owner can attach CORS headers to specify exactly which requests can be allowed in the _headers file for fine-grained and explicit control.
For example, the use of the asterisk will enable any origin to request any asset from your Pages deployment:
/*
  Access-Control-Allow-Origin: *
To be more restrictive and limit requests to only be allowed from a ‘staging’ subdomain, we can do the following:
To support all these use cases for custom headers, we had to build a new engine to determine which rules to apply for each incoming request. Backed, of course, by Workers, this engine supports splats and placeholders, and allows you to include those matched values in your headers.
Although we don’t support all of its features, we’ve modeled this matching engine after the URLPattern specification which was recently shipped with Chrome 95. We plan to be able to fully implement this specification for custom headers once URLPattern lands in the Workers runtime, and there should hopefully be no breaking changes to migrate.
Enhanced support for redirects
With this same engine, we’re bringing these features to your _redirects file as well. You can now configure your redirects with splats, placeholders and status codes as shown in the example below:
Custom headers and redirects for Cloudflare Pages can be configured today. Check out our documentation to get started, and let us know how you’re using it in our Discord server. We’d love to hear about what this unlocks for your projects!
Coming up…
And finally, if a _headers file and enhanced support for _redirects just isn’t enough for you, we also have something big coming very soon which will give you the power to build even more powerful projects. Stay tuned!
During Developer Week a few months ago, we opened up the Beta for Cloudflare for SaaS: a one-stop shop for SaaS providers looking to provide fast load times, unparalleled redundancy, and the strongest security to their customers.
Since then, we’ve seen numerous developers integrate with our technology, allowing them to spend their time building out their solution instead of focusing on the burdens of running a fast, secure, and scalable infrastructure — after all, that’s what we’re here for.
Today, we are very excited to announce that Cloudflare for SaaS is generally available, so that every customer, big and small, can use Cloudflare for SaaS to continue scaling and building their SaaS business.
What is Cloudflare for SaaS?
If you’re running a SaaS company, you have customers that are fully reliant on you for your service. That means you’re responsible for keeping their domain fast, secure, and protected. But this isn’t simple. There’s a long checklist you need to get through to put a solution in your customers’ hands:
Set up an origin server
Encrypt your customers’ traffic
Keep your customers online
Boost the performance of global customers
Support vanity domains
Protect against attacks and bots
Scale for growth
Provide insights and analytics
And on top of that, you need to also focus on building out your solution and your business. As a developer or startup with limited resources, this can delay your product launch by weeks or months.
That’s what we’re here to help with! We have numerous engineering teams whose sole focus is to work on products that take care of each one of these tasks, so you don’t have to!
The Cloudflare solution:
Set up an origin server → Workers
Encrypt your customers’ traffic → SSL for SaaS
Keep your customers online → Cloudflare’s global Anycast network
Boost the performance of global customers → Argo Smart Routing/Cache
Support vanity domains → Custom Hostnames
Protect against attacks and bots → WAF and Bot Management
Scale for growth → Workers
Provide insights and analytics → Custom Hostname Analytics
Pricing, Made for Developers
Starting today, Cloudflare for SaaS is available to purchase on Free, Pro, and Business plans. We wanted to make sure that the pricing made sense for developers. At the time of building, you don’t know how many customers you’ll have, so we wanted to offer flexibility by keeping the pricing as simple as possible: only pay for the customers you use.
Each customer domain using the service is called a Custom Hostname. For each Custom Hostname, we automatically provision a TLS certificate. But not just that! Beyond the TLS certificate, each of your Custom Hostnames inherits the full suite of Cloudflare products that you set up on your SaaS zone. From Bot Management to Argo Smart Routing, you can extend these add-ons that protect and accelerate your domain to your customers.
Custom Hostnames cost two dollars per month. We will only charge you after each Custom Hostname has been onboarded, adjusted according to when you created it. That means that if you created 10 Custom Hostnames at the start of the month and 10 Custom Hostnames halfway through, at the end of the month you will be billed $30.
This way, you’re only charged for the Custom Hostnames that you provision. It’s also a great incentive to make sure you clean up after your churned customers.
If you’re an Enterprise customer and want to learn more about the benefits that you can from Cloudflare for SaaS, make sure you check out our blog post about the latest developments.
Show us what you’re building!
During the beta alone, we’ve seen incredible projects built out on the platform. We wanted to showcase these developers to show you what’s possible. And even better, some of these have been built on our Workers platform! We’d love to see what you’re working on. Join our Discord channel and showcase your work! Have feature requests for us? Let us know!
mmm.page: Simple Personal Websites
mmm.page is a drag-and-drop website builder that makes it dead simple to create auto-responsive, collage-like websites: websites with overlapping text, images, GIFs, YouTube videos, Spotify embeds, and (a lot) more. To make it easier, all the standard website tedium — uptime, usability, performance, reliability, responsiveness, SEO, etc. — are handled under the hood so all you have to worry about is adding content and arranging it how you want.
Under their hood is Cloudflare. Cloudflare’s CDN allows both the flexibility of server-side pages as well as the instant loading times of static pages — not to mention an 80% reduction in server costs. Custom Hostnames alone saved months of development time by handling domain names and SSL management (which are otherwise tricky to get perfect and reliable).
They’ve used Workers for increasingly more tasks that would’ve otherwise taken an order of magnitude more time if implemented with their current backend monolith — the ease of deployment and comparatively low cost of Workers is something that keeps them coming back.
The longer-term hope is for pages to be used as a sort of beacon signal, an easy-to-make yet unbounded way to express to others the things you’re interested in, especially for things that aren’t so easily describable or captured in words. They look forward to a world of a ton more DIY micro-sites. Cloudflare has been crucial in taking care of much of the difficult technical plumbing and giving them more time to work on designs and features that get them closer to this hope.
Lightfunnels
Lightfunnels is a performance driven e-commerce and lead generation platform. It focuses on delivering fast, reliable, and highly converting sales funnels to its users and their customers.
With Cloudflare for SaaS, Lightfunnels allows users to preserve their brand by easily connecting their own domain names with SSL to use on their funnels.
The platform handles large e-commerce traffic volume through Cloudflare Workers. This helps Lightfunnels serve pages from the closest edge to the customer, wherever they are in the world, allowing for blazing fast page load speeds.
Workers also come with a powerful caching API that eliminates a great percentage of back-end trips and reduces the stress on their servers.
“Our aim is to build the best performing e-commerce and lead generation platform on the market. Page load speeds play a significant role in performance. Using Cloudflare for SaaS along with Cloudflare Workers made building a reliable, secure, and fast infrastructure a breeze.” – Yassir Ennazk, Co-founder & CEO at Lightfunnels
Ventrata
Ventrata is a SaaS multi-channel booking platform for large attractions and tour operators.They power booking sites and B2B booking portals for clients that run on other domains. Cloudflare for SaaS has allowed them to leverage all of Cloudflare’s tools, including Firewall, image caching, Workers, and free TLS certificates on Custom Hostnames, while allowing their clients to keep full control of their brand. Their implementation involved just 4 lines of code without any infrastructure/DevOps help required, which would have been impossible before.
Currently a part of the Beta?
If you were accepted as a part of the Cloudflare for SaaS Beta, you will get a notice next week about migrating to the paid version.
Help build a better Internet
Want to be a part of the Cloudflare team and work on the products that power Cloudflare for SaaS? We’re hiring!
I work on Cloudflare Tunnel, which lets customers quickly connect their private services and networks through the Cloudflare network without having to expose their public IPs or ports through their firewall. Tunnel is managed for users by cloudflared, a tool that runs on the same network as the private services. It proxies traffic for these services via Cloudflare, and users can then access these services securely through the Cloudflare network.
Recently, I was trying to get Cloudflare Tunnel to connect to the Cloudflare network using a UDP protocol, QUIC. While doing this, I ran into an interesting connectivity problem unique to UDP. In this post I will talk about how I went about debugging this connectivity issue beyond the land of firewalls, and how some interesting differences between UDP and TCP came into play when sending network packets.
How does Cloudflare Tunnel work?
cloudflared works by opening several connections to different servers on the Cloudflare edge. Currently, these are long-lived TCP-based connections proxied over HTTP/2 frames. When Cloudflare receives a request to a hostname, it is proxied through these connections to the local service behind cloudflared.
While our HTTP/2 protocol mode works great, we’d like to improve a few things. First, TCP traffic sent over HTTP/2 is susceptible to Head of Line (HoL) blocking — this affects both HTTP traffic and traffic from WARP routing. Additionally, it is currently not possible to initiate communication from cloudflared’s HTTP/2 server in an efficient way. With the current Go implementation of HTTP/2, we could use Server-Sent Events, but this is not very useful in the scheme of proxying L4 traffic.
The upgrade to QUIC solves possible HoL blocking issues and opens up avenues that allow us to initiate communication from cloudflared to a different cloudflared in the future.
Naturally, QUIC required a UDP-based listener on our edge servers which cloudflared could connect to. We already connect to a TCP-based listener for the existing protocols, so this should be nice and easy, right?
Failed to dial to the edge
Things weren’t as straightforward as they first looked. I added a QUIC listener on the edge, and the ability for cloudflared to connect to this new UDP-based listener. I tried to run my brand new QUIC tunnel and this happened.
$  cloudflared tunnel run --protocol quic my-tunnel
2021-09-17T18:44:11Z ERR Failed to create new quic connection, err: failed to dial to edge: timeout: no recent network activity
cloudflared wasn’t even establishing a connection to the edge. I started looking at the obvious places first. Did I add a firewall rule allowing traffic to this port? Check. Did I have iptables rules ACCEPTing or DROPping appropriate traffic for this port? Check. They seemed to be in order. So what else could I do?
tcpdump all the packets
I started by logging for UDP traffic on the machine my server was running on to see what could be happening.
$  sudo tcpdump -n -i eth0 port 7844 and udp
tcpdump: verbose output suppressed, use -v or -vv for full protocol decode
listening on eth0, link-type EN10MB (Ethernet), capture size 262144 bytes
14:44:27.742629 IP 173.13.13.10.50152 > 198.41.200.200.7844: UDP, length 1252
14:44:27.743298 IP 203.0.113.0.7844 > 173.13.13.10.50152: UDP, length 37
Looking at this tcpdump helped me understand why I had no connectivity! Not only was this port getting UDP traffic but I was also seeing traffic flow out. But there seemed to be something strange afoot. Incoming packets were being sent to 198.41.200.200:7844 while responses were being sent back from 203.0.113.0:7844 (this is an example IP used for illustration purposes) instead.
Why is this a problem? If a host (in this case, the server) chooses an address from a network unable to communicate with a public Internet host, it is likely that the return half of the communication will never arrive. But wait a minute. Why is some other IP getting prioritized over a source address my packets were already being sent to? Let’s take a deeper look at some IP addresses. (Note that I’ve deliberately oversimplified and scrambled results to minimally illustrate the problem)
$  ip addr list
eth0: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1600 qdisc noqueue state UP group default qlen 1000
inet 203.0.113.0/32 scope global eth0
inet 198.41.200.200/32 scope global eth0
$ ip route show
default via 203.0.113.0 dev eth0
So this was clearly why the server was working fine on my machine but not on the Cloudflare edge servers. It looks like I have multiple IPs on the interface my service is bound to. The IP that is the default route is being sent back as the source address of the packet.
Why does this work for TCP but not UDP?
Connection-oriented protocols, like TCP, initiate a connection (connect()) with a three-way handshake. The kernel therefore maintains a state about ongoing connections and uses this to determine the source IP address at the time of a response.
Because UDP (unless SOCK_SEQPACKET is involved) is connectionless, the kernel cannot maintain state like TCP does. The recvfrom system call is invoked from the server side and tells who the data comes from. Unfortunately, recvfrom does not tell us which IP this data is addressed for. Therefore, when the UDP server invokes the sendto system call to respond to the client, we can only tell it which address to send the data to. The responsibility of determining the source-address IP then falls to the kernel. The kernel has certain heuristics that it uses to determine the source address. This may or may not work, and in the ip routes example above, these heuristics did not work. The kernel naturally (and wrongly) picks the address of the default route to respond with.
Telling the kernel what to do
I had to rely on my application to set the source address explicitly and therefore not rely on kernel heuristics.
Linux has some generic I/O system calls, namely recvmsg and sendmsg. Their function signatures allow us to both read or write additional out-of-band data we can pass the source address to. This control information is passed via the msghdr struct’s msg_control field.
ssize_t sendmsg(int socket, const struct msghdr *message, int flags)
ssize_t recvmsg(int socket, struct msghdr *message, int flags);

struct msghdr {
     void    *   msg_name;   /* Socket name          */
     int     msg_namelen;    /* Length of name       */
     struct iovec *  msg_iov;    /* Data blocks          */
     __kernel_size_t msg_iovlen; /* Number of blocks     */
     void    *   msg_control;    /* Per protocol magic (eg BSD file descriptor passing) */
    __kernel_size_t msg_controllen; /* Length of cmsg list */
     unsigned int    msg_flags;
};
We can now copy the control information we’ve gotten from recvmsg back when calling sendmsg, providing the kernel with information about the source address.The library I used (https://github.com/lucas-clemente/quic-go) had a recent update that did exactly this! I pulled the changes into my service and gave it a spin.
But alas. It did not work! A quick tcpdump showed that the same source address was being sent back. It seemed clear from reading the source code that the recvmsg and sendmsg were being called with the right values. It did not make sense.
So I had to see for myself if these system calls were being made.
strace all the system calls
strace is an extremely useful tool that tracks all system calls and signals sent/received by a process. Here’s what it had to say. I’ve removed all the information not relevant to this specific issue.
Let’s start with recvmsg . We can clearly see that the ipi_addr for the source is being passed correctly: ipi_addr=inet_addr(“172.16.90.131”). This part works as expected. Looking at sendmsg almost instantly tells us where the problem is. The field we want, ip_spec_dst is not being set as we make this system call. So the kernel continues to make wrong guesses as to what the source address may be.
This turned out to be a bug where the library was using IPROTO_TCP instead of IPPROTO_IPV4 as the control message level while making the sendmsg call. Was that it? Seemed a little anticlimactic. I submitted a slightly more typesafe fix and sure enough, straces now showed me what I was expecting to see.
While the programmatic bug causing this issue was a trivial one, the journey into systematically discovering the issue and understanding how Linux internals worked for UDP along the way turned out to be very rewarding for me. It also reiterated my belief that tcpdump and strace are indeed invaluable tools in anybody’s arsenal when debugging network problems.
What’s next?
You can give this a try with the latest cloudflared release at https://github.com/cloudflare/cloudflared/releases/latest. Just remember to set the protocol flag to quic. We plan to leverage this new mode to roll out some exciting new features for Cloudflare Tunnel. So upgrade away and keep watching this space for more information on how you can take advantage of this.
In the midst of the hottest summer on record, Cloudflare held its first ever Impact Week. We announced a variety of products and initiatives that aim to make the Internet and our planet a better place, with a focus on environmental, social, and governance projects. Today, we’re excited to share an update on Crawler Hints, an initiative announced during Impact Week. Crawler Hints is a service that improves the operating efficiency of the approximately 45% of Internet traffic that comes from web crawlers and bots.
Crawler Hints achieves this efficiency improvement by ensuring that crawlers get information about what they’ve crawled previously and if it makes sense to crawl a website again.
Today we are excited to announce two updates for Crawler Hints:
The first: Crawler Hints now supports IndexNow, a new protocol that allows websites to notify search engines whenever content on their website content is created, updated, or deleted. By collaborating with Microsoft and Yandex, Cloudflare can help improve the efficiency of their search engine infrastructure, customer origin servers, and the Internet at large.
The second: Crawler Hints is now generally available to all Cloudflare customers for free. Customers can benefit from these more efficient crawls with a single button click. If you want to enable Crawler Hints, you can do so in the Cache Tab of the Dashboard.
What problem does Crawler Hints solve?
Crawlers help make the Internet work. Crawlers are automated services that travel the Internet looking for… well, whatever they are programmed to look for. To power experiences that rely on indexing content from across the web, search engines and similar services operate massive networks of bots that crawl the Internet to identify the content most relevant to a user query. But because content on the web is always changing, and there is no central clearinghouse for when these changes happen on websites, search engine crawlers have a Sisyphean task. They must continuously wander the Internet, making guesses on how frequently they should check a given site for updates to its content.
Companies that run search engines have worked hard to make the process as efficient as possible, pushing the state-of-the-art for crawl cadence and infrastructure efficiency. But there remains one clear area of waste: excessive crawl.
At Cloudflare, we see traffic from all the major search crawlers, and have spent the last year studying how often these bots revisit a page that hasn’t changed since they last saw it. Every one of these visits is a waste. And, unfortunately, our observation suggests that 53% of this crawler traffic is wasted.
With Crawler Hints, we expect to make this task a bit more tractable by providing an additional heuristic to the people who run these crawlers. This will allow them to know when content has been changed or added to a site instead of relying on preferences or previous changes that might not reflect the true change cadence for a site. Crawler Hints aims to increase the proportion of relevant crawls and limit crawls that don’t find fresh content, improving customer experience and reducing the need for repeated crawls.
Cloudflare sits in a unique position on the Internet to help give crawlers hints about when they should recrawl a site. Don’t knock on a website’s door every 30 seconds to see if anything is new when Cloudflare can proactively tell your crawler when it’s the best time to index new or changed content. That’s Crawler Hints in a nutshell!
If you want to learn more about Crawler Hints, see the original blog.
What is IndexNow?
IndexNow is a standard that was written by Microsoft and Yandex search engines. The standard aims to provide an efficient manner of signaling to search engines and other crawlers for when they should crawl content. Cloudflare’s Crawler Hints now supports IndexNow.
In its simplest form, IndexNow is a simple ping so that search engines know that a URL and its content has been added, updated, or deleted, allowing search engines to quickly reflect this change in their search results. – www.indexnow.org
By enabling Crawler Hints on your website, with the simple click of a button, Cloudflare will take care of signaling to these search engines when your content has changed via the IndexNow protocol. You don’t need to do anything else!
What does this mean for search engine operators? With Crawler Hints you’ll receive a near real-time, pushed feed of change events of Cloudflare websites (that have opted in). This, in turn, will dramatically improve not just the quality of your results, but also the energy efficiency of running your bots.
Collaborating with Industry leaders
Cloudflare is in a unique position to have a sizable portion of the Internet proxied behind us. As a result, we are able to see trends in the way bots access web resources. That visibility allows us to be proactive about signaling which crawls are required vs. not. We are excited to work with partners to make these insights useful to our customers. Search engines are key constituents in this equation. We are happy to collaborate and share this vision of a more efficient Internet with Microsoft Bing, and Yandex. We have been testing our interaction via IndexNow with Bing and Yandex for months with some early successes.
This is just the beginning. Crawler Hints is a continuous process that will require working with more and more partners to improve Internet efficiency more generally. While this may take time and participation from other key parts of the industry, we are open to collaborate with any interested participant who relies on crawling to power user experiences.
“The cache data from CDNs is a really valuable signal for content freshness. Cloudflare, as one of the top CDNs, is key in the adoption of IndexNow to become an industry-wide standard with a large portion of the internet actually using it. Cloudflare has built a really easy 1-click button for their users to start using it right away. Cloudflare’s mission of helping build a better Internet resonates well with why I started IndexNow i.e. to build a more efficient and effective Search.” – Fabrice Canel, Principal Program Manager
“Yandex is excited to join IndexNow as part of our long-term focus on sustainability. We have been working with the Cloudflare team in early testing to incorporate their caching signals in our crawling mechanism via the IndexNow API. The results are great so far.” – Maxim Zagrebin, Head of Yandex Search
“DuckDuckGo is supportive of anything that makes search more environmentally friendly and better for end users without harming privacy. We’re looking forward to working with Cloudflare on this proposal.” – Gabriel Weinberg, CEO and Founder
How do Cloudflare customers benefit?
Crawler Hints doesn’t just benefit search engines. For our customers and origin owners, Crawler Hints will ensure that search engines and other bot-powered experiences will always have the freshest version of your content, translating into happier users and ultimately influencing search rankings. Crawler Hints will also mean less traffic hitting your origin, improving resource consumption. Moreover, your site performance will be improved as well: your human customers will not be competing with bots!
And for Internet users? When you interact with bot-fed experiences — which we all do every day, whether we realize it or not, like search engines or pricing tools — these will now deliver more useful results from crawled data, because Cloudflare has signaled to the owners of the bots the moment they need to update their results.
How can I enable Crawler Hints for my website?
Crawler Hints is free to use for all Cloudflare customers and promises to revolutionize web efficiency. If you’d like to see how Crawler Hints can benefit how your website is indexed by the worlds biggest search engines, please feel free to opt-into the service:
Sign in to your Cloudflare Account.
In the dashboard, navigate to the Cache tab.
Click on the Configuration section.
Locate the Crawler Hints sign up card and enable. It’s that easy.
Once you’ve enabled it, we will begin sending hints to search engines about when they should crawl particular parts of your website. Crawler Hints holds tremendous promise to improve the efficiency of the Internet.
What’s next?
We’re thrilled to collaborate with industry leaders Microsoft Bing, and Yandex to bring IndexNow to Crawler Hints, and to bring Crawler Hints to a wide audience in general availability. We look forward to working with additional companies who run crawlers to help make this process more efficient for the whole Internet.
Cloudflare Tunnel connects your infrastructure to Cloudflare. Your team runs a lightweight connector in your environment, cloudflared, and services can reach Cloudflare and your audience through an outbound-only connection without the need for opening up holes in your firewall.
Whether the services are internal apps protected with Zero Trust policies, websites running in Kubernetes clusters in a public cloud environment, or a hobbyist project on a Raspberry Pi — Cloudflare Tunnel provides a stable, secure, and highly performant way to serve traffic.
Starting today, with our new UI in the Cloudflare for Teams Dashboard, users who deploy and manage Cloudflare Tunnel at scale now have easier visibility into their tunnels’ status, routes, uptime, connectors, cloudflared version, and much more. On the Teams Dashboard you will also find an interactive guide that walks you through setting up your first tunnel.
Getting Started with Tunnel
We wanted to start by making the tunnel onboarding process more transparent for users. We understand that not all users are intimately familiar with the command line nor are they deploying tunnel in an environment or OS they’re most comfortable with. To alleviate that burden, we designed a comprehensive onboarding guide with pathways for MacOS, Windows, and Linux for our two primary onboarding flows:
Our new onboarding guide walks through each command required to create, route, and run your tunnel successfully while also highlighting relevant validation commands to serve as guardrails along the way. Once completed, you’ll be able to view and manage your newly established tunnels.
Managing your tunnels
When thinking about the new user interface for tunnel we wanted to concentrate our efforts on how users gain visibility into their tunnels today. It was important that we provide the same level of observability, but through the lens of a visual, interactive dashboard. Specifically, we strove to build a familiar experience like the one a user may see if they were to run cloudflared tunnel list to show all of their tunnels, or cloudflared tunnel info if they wanted to better understand the connection status of a specific tunnel.
In the interface, you can quickly search by name or filter by name, status, uptime, or creation date. This allows users to easily identify and manage the tunnels they need, when they need them. We also included other key metrics such as Status and Uptime.
A tunnel’s status depends on the health of its connections:
Active: This means your tunnel is running and has a healthy connection to the Cloudflare network.
Inactive: This means your tunnel is not running and is not connected to Cloudflare.
Degraded: This means one or more of your four long-lived TCP connections to Cloudflare have been disconnected, but traffic is still being served to your origin.
A tunnel’s uptime is also calculated by the health of its connections. We perform this calculation by determining the UTC timestamp of when the first (of four) long-lived TCP connections is established with the Cloudflare Edge. In the event this single connection is terminated, we will continue tracking uptime as long as one of the other three connections continues to serve traffic. If no connections are active, Uptime will reset to zero.
Tunnel Routes and Connectors
Last year, shortly after the announcement of Named Tunnels, we released a new feature that allowed users to utilize the same Named Tunnel to serve traffic to many different services through the use of Ingress Rules. In the new UI, if you’re running your tunnels in this manner, you’ll be able to see these various services reflected by hovering over the route’s value in the dashboard. Today, this includes routes for DNS records, Load Balancers, and Private IP ranges.
Even more recently, we announced highly available and highly scalable instances of cloudflared, known more commonly as “cloudflared replicas.” To view your cloudflared replicas, select and expand a tunnel. Then you will identify how many cloudflared replicas you’re running for a given tunnel, as well as the corresponding connection status, data center, IP address, and version. And ultimately, when you’re ready to delete a tunnel, you can do so directly from the dashboard as well.
What’s next
Moving forward, we’re excited to begin incorporating more Cloudflare Tunnel analytics into our dashboard. We also want to continue making Cloudflare Tunnel the easiest way to connect to Cloudflare. In order to do that, we will focus on improving our onboarding experience for new users and look forward to bringing more of that functionality into the Teams Dashboard. If you have things you’re interested in having more visibility around in the future, let us know below!
Cloudflare provides our customers with security tools that help them protect their Internet applications against malicious or undesired traffic. Malicious traffic can include scraping content from a website, spamming form submissions, and a variety of other cyberattacks. To protect themselves from these types of threats while minimizing the blocking of legitimate site visitors, Cloudflare’s customers need to be able to identify traffic that might be malicious.
We know some of our customers rely on IP addresses to distinguish between traffic from legitimate users and potentially malicious users. However, in many cases the IP address of a request does not correspond to a particular user or even device. Furthermore, Cloudflare believes that in the long term, the IP address will be an even more unreliable signal for identifying the origin of a request. We envision a day where IP will be completely unassociated with identity. With that vision in mind, multi-user IP address detection represents our first step: pointing out situations where the IP address of a request cannot be assumed to be a single user. This gives our customers the ability to make more judicious decisions when responding to traffic from an IP address, instead of indiscriminately treating that traffic as though it was coming from a single user.
Historically, companies commonly treated IP addresses like mobile phone numbers: each phone number in theory corresponds to a single person. If you get several spam calls within an hour from the same phone number, you might safely assume that phone number represents a single person and ignore future calls or even block that number. Similarly, many Internet security detection engines rely on IP addresses to discern which requests are legitimate and which are malicious.
However, this analogy is flawed and can present a problem for security. In practice, IP addresses are more like postal addresses because they can be shared by more than one person at a time (and because of NAT and CG-NAT the number of people sharing an IP can be very large!). Many existing Internet security tools accept IP addresses as a reliable way to distinguish between site visitors. However, if multiple visitors share the same IP address, security products cannot rely on the IP address as a unique identifying signal. Thousands of requests from thousands of different users need to be treated differently from thousands of requests from the same user. The former is likely normal traffic, while the latter is almost certainly automated, malicious traffic.
For example, if several people in the same apartment building accessed the same site, it’s possible all of their requests would be routed through a middlebox operated by their Internet service provider that has only one IP address. But this sudden series of requests from the same IP address could closely resemble the behavior of a bot. In this case, IP addresses can’t be used by our customers to distinguish this activity from a real threat, leading them to mistakenly block or challenge their legitimate site visitors.
By adding multi-user IP address detection to Cloudflare products, we’re improving the quality of our detection techniques and reducing false positives for our customers.
Examples of Multi-User IP Addresses
Multi-user IP addresses take on many forms. When your company uses an enterprise VPN, for example, employees may share the same IP address when accessing external websites. Other types of VPNs and proxies also place multiple users behind a single IP address.
Another type of multi-user IP address originated from the core communications protocol of the Internet. IPv4 was developed in the 1980s. The protocol uses a 32-bit address space, allowing for over four billion unique addresses. Today, however, there are many times more devices than IPv4 addresses, meaning that not every device can have a unique IP address. Though IPv6 (IPv4’s successor protocol) solves the problem with 128-bit addresses (supporting 2128 unique addresses), IPv4 still routes the majority of Internet traffic (76% of human-only traffic is IPv4, as shown on Cloudflare Radar).
To solve this issue, many devices in the same Local Area Network (LAN) can share a single Internet-addressable IP address to communicate with the public Internet, while using private Internet addresses to communicate within the LAN. Since private addresses are to be used only within a LAN, different LANs can number their hosts using the same private IP address space. The Internet gateway of the LAN does the Network Address Translation (NAT), namely takes messages which arrive on that single public IP and forwards them to the private IP of the appropriate device on their local network. In effect it’s similar to how everyone in an office building shares the same street address, and the front desk worker is responsible for sorting out what mail was meant for which person.
While NAT allows multiple devices behind the same Internet gateway to share the same public IP address, the explosive growth of the Internet population necessitated further reuse of the limited IPv4 address space. Internet Service Providers (ISPs) required users in different LANs to share the same IP address for their service to scale. Carrier-Grade Network Address Translation (CG-NAT) emerged as another solution for address space reuse. Network operators can use CG-NAT middleboxes to translate hundreds or thousands of private IPv4 addresses into a single (or pool of) public IPv4 address. However, this sharing is not without side-effects. CG-NAT results in IP addresses that cannot be tied to single devices, users, or broadband subscriptions, creating issues for security products that rely on the IP address as a way to distinguish between requests from different users.
What We Built
We built a tool to help our customers detect when a /24 IP prefix (set of IP addresses that have the same first 24 bits) is likely to contain multi-user IP addresses, so they can more finely tune the security rules that protect their websites. In order to identify multi-user IP prefixes, we leverage both internal data and public data sources. Within this data, we look at a few key parameters.
Each TCP connection between a source (client) and a destination (server) is identified by 4 identifiers (source IP, source port, destination IP, destination port)
When an Internet user visits a website, the underlying TCP stack opens a number of connections in order to send and receive data from remote servers. Each connection is identified by a 4-tuple (source IP, source port, destination IP, destination port). Repeating requests from the same web client will likely be mapped to the same source port, so the number of distinct source ports can serve as a good indication of the number of distinct client applications. By counting the number of open source ports for a given IP address, you can estimate whether this address is shared by multiple users.
User agents provide device-reported information about themselves such as browser and operating system versions. For multi-user IP detection, you can count the number of distinct user agents in requests from a given IP. To avoid overcounting web clients per device, you can exclude requests that are identified as triggered by bots and we only count requests from user agents that are used by web browsers. There are some tradeoffs to this approach: some users may use multiple web browsers and some other users may have exactly the same user agent. Nevertheless, past research has shown that the number of unique web browser user agents is the best tradeoff to most accurately determine CG-NAT usage.
Mozilla/5.0 (X11; Linux x86_64; rv:92.0) Gecko/20100101 Firefox/92.0
For our inferences, we group IP addresses to their corresponding /24 IP prefix. The figure below shows the distribution of browser User Agents per /24 IP prefix, based on data accumulated over the period of a day. About 35% of the prefixes have more than 100 different browser clients behind them.
Our service also uses other publicly available data sources to further refine the accuracy of our identification and to classify the type of multi-user IP address. For example, we collect data from PeeringDB, which is a database where network operators self-identify their network type, traffic levels, interconnection points, and peering policy. This data only covers a fraction of the Internet’s autonomous systems (ASes). To overcome this limitation, we use this data and our own data (number of requests per AS, number of websites in each AS) to infer AS type. We also use external data sources such as IRR to identify requests from VPNs and proxy servers.
These details (especially AS type) can provide more information on the type of multi-user IP address. For instance, CG-NAT systems are almost exclusively deployed by broadband providers, so by inferring the AS type (ISP, CDN, Enterprise, etc.), we can more confidently infer the type of each multi-user IP address. A scheduled job periodically executes code to pull data from these sources, process it, and write the list of multi-user IP addresses to a database. That IP info data is then ingested by another system that deploys it to Cloudflare’s edge, enabling our security products to detect potential threats with minimal latency.
To validate our inferences for which IP addresses are multi-user, we created a dataset relying on separate data and measurements which we believe are more reliable indicators. One method we used was running traceroute queries through RIPE Atlas, from each RIPE Atlas probe to the probe’s public IP address. By examining the traceroute hops, we can determine if an IP is behind a CG-NAT or another middlebox. For example, if an IP is not behind a CG-NAT, the traceroute should terminate immediately or just have one hop (likely a home NAT). On the other hand, if a traceroute path includes addresses within the RFC 6598 CGNAT prefix or other hops in the private or shared address space, it is likely the corresponding probe is behind CG-NAT.
To further improve our validation datasets, we’re also reaching out to our ISP partners to confirm the known IP addresses of CG-NATs. As we refine our validation data, we can more accurately tune our multi-user IP address inference parameters and provide a better experience to ISP customers on sites protected by Cloudflare security products.
The multi-user IP detection service currently recognizes approximately 500,000 unique multi-user IP addresses and is being tuned to further improve detection accuracy. Be on the lookout for an upcoming technical blog post, where we will take a deeper look at the system we built and the metrics collected after running this service for a longer period of time.
How Will This Impact Bot Management and Rate Limiting Customers?
Our initial launch will integrate multi-user IP address detection into our Bot Management and Rate Limiting products.
The three modules that comprise the bot detection system.
The Cloudflare Bot Management product has five detection mechanisms. The integration will improve three of the five: the machine learning (ML) detection mechanism, the heuristics engine, and the behavioral analysis models. Multi-user IP addresses and their types will serve as additional features to train our ML model. Furthermore, logic will be added to ensure multi-user IP addresses are treated differently in our other detection mechanisms. For instance, our behavioral analysis detection mechanism shouldn’t treat a series of requests from a multi-user IP the same as a series of requests from a single-user IP. There won’t be any new ways to see or interact with this feature, but you should expect to see a decrease in false positive bot detections involving multi-user IP addresses.
The integration with Rate Limiting will allow us to increase the set rate limiting threshold when receiving requests coming from multi-user IP addresses. The factor by which we increase the threshold will be conservative so as not to completely bypass the rate limit. However, the increased threshold should greatly reduce cases where legitimate users behind multi-user IP addresses are blocked or challenged.
We will also continue to make improvements to our multi-user IP address detection system to incorporate additional data sources and improve accuracy. One data source would allow us to get a fraction for the estimated number of subscribers over the total number of IPs advertised (owned) by an AS. ASes that have more estimated subscribers than available IPs would have to rely on CG-NAT to provide service to all subscribers.
As mentioned above, with the help of our ISP partners we hope to improve the validation datasets we use to test and refine the accuracy of our inferences. Additionally, our integration with Bot Management will also unlock an opportunity to create a feedback loop that further validates our datasets. The challenge solve rate (CSR) is a metric generated by Bot Management that indicates the proportion of requests that were challenged and solved (and thus assumed to be human). Examining requests with both high and low CSRs will allow us to check if the multi-user IP addresses we have initially identified indeed represent mostly legitimate human traffic that our customers should not block.
The continued adoption of IPv6 might someday make CG-NATs and other IPv4 sharing technologies irrelevant, as the address space will no longer be limited. This could reduce the prevalence of multi-user IP addresses. However, with the development of new networking technologies that obfuscate IP addresses for user privacy (for example, IPv6 randomized address assignment), it seems unlikely it will become any easier to tie an IP address to a single user. Cloudflare firmly believes that eventually, IP will be completely unassociated with identity.
Yet in the short term, we recognize that IP addresses still play a pivotal role for the security of our customers. By integrating this multi-user IP address detection capability into our products, we aim to deliver a more free and fluid experience for everyone using the Internet.
Today we’re announcing a public demo and an open-sourced Go implementation of a next-generation, privacy-preserving compromised credential checking protocol called MIGP (“Might I Get Pwned”, a nod to Troy Hunt’s “Have I Been Pwned”). Compromised credential checking services are used to alert users when their credentials might have been exposed in data breaches. Critically, the ‘privacy-preserving’ property of the MIGP protocol means that clients can check for leaked credentials without leaking any information to the service about the queried password, and only a small amount of information about the queried username. Thus, not only can the service inform you when one of your usernames and passwords may have become compromised, but it does so without exposing any unnecessary information, keeping credential checking from becoming a vulnerability itself. The ‘next-generation’ property comes from the fact that MIGP advances upon the current state of the art in credential checking services by allowing clients to not only check if their exact password is present in a data breach, but to check if similar passwords have been exposed as well.
For example, suppose your password last year was amazon20\$, and you change your password each year (so your current password is amazon21\$). If last year’s password got leaked, MIGP could tell you that your current password is weak and guessable as it is a simple variant of the leaked password.
The MIGP protocol was designed by researchers at Cornell Tech and the University of Wisconsin-Madison, and we encourage you to read the paper for more details. In this blog post, we provide motivation for why compromised credential checking is important for security hygiene, and how the MIGP protocol improves upon the current generation of credential checking services. We then describe our implementation and the deployment of MIGP within Cloudflare’s infrastructure.
Our MIGP demo and public API are not meant to replace existing credential checking services today, but rather demonstrate what is possible in the space. We aim to push the envelope in terms of privacy and are excited to employ some cutting-edge cryptographic primitives along the way.
The threat of data breaches
Data breaches are rampant. The regularity of news articles detailing how tens or hundreds of millions of customer records have been compromised have made us almost numb to the details. Perhaps we all hope to stay safe just by being a small fish in the middle of a very large school of similar fish that is being predated upon. But we can do better than just hope that our particular authentication credentials are safe. We can actually check those credentials against known databases of the very same compromised user information we learn about from the news.
Many of the security breaches we read about involve leaked databases containing user details. In the worst cases, user data entered during account registration on a particular website is made available (often offered for sale) after a data breach. Think of the addresses, password hints, credit card numbers, and other private details you have submitted via an online form. We rely on the care taken by the online services in question to protect those details. On top of this, consider that the same (or quite similar) usernames and passwords are commonly used on more than one site. Our information across all of those sites may be as vulnerable as the site with the weakest security practices. Attackers take advantage of this fact to actively compromise accounts and exploit users every day.
Credential stuffing is an attack in which malicious parties use leaked credentials from an account on one service to attempt to log in to a variety of other services. These attacks are effective because of the prevalence of reused credentials across services and domains. After all, who hasn’t at some point had a favorite password they used for everything? (Quick plug: please use a password manager like LastPass to generate unique and complex passwords for each service you use.)
Website operators have (or should have) a vested interest in making sure that users of their service are using secure and non-compromised credentials. Given the sophistication of techniques employed by malevolent actors, the standard requirement to “include uppercase, lowercase, digit, and special characters” really is not enough (and can be actively harmful according to NIST’s latest guidance). We need to offer better options to users that keep them safe and preserve the privacy of vulnerable information. Dealing with account compromise and recovery is an expensive process for all parties involved.
Users and organizations need a way to know if their credentials have been compromised, but how can they do it? One approach is to scour dark web forums for data breach torrent links, download and parse gigabytes or terabytes of archives to your laptop, and then search the dataset to see if their credentials have been exposed. This approach is not workable for the majority of Internet users and website operators, but fortunately there’s a better way — have someone with terabytes to spare do it for you!
Making compromise checking fast and easy
This is exactly what compromised credential checking services do: they aggregate breach datasets and make it possible for a client to determine whether a username and password are present in the breached data. Have I Been Pwned (HIBP), launched by Troy Hunt in 2013, was the first major public breach alerting site. It provides a service, Pwned Passwords, where users can efficiently check if their passwords have been compromised. The initial version of Pwned Passwords required users to send the full password hash to the service to check if it appears in a data breach. In a 2018 collaboration with Cloudflare, the service was upgraded to allow users to run range queries over the password dataset, leaking only the salted hash prefix rather than the entire hash. Cloudflare continues to support the HIBP project by providing CDN and security support for organizations to download the raw Pwned Password datasets.
The HIBP approach was replicated by Google Password Checkup (GPC) in 2019, with the primary difference that GPC alerts are based on username-password pairs instead of passwords alone, which limits the rate of false positives. Enzoic and Microsoft Password Monitor are two other similar services. This year, Cloudflare also released Exposed Credential Checks as part of our Web Application Firewall (WAF) to help inform opted-in website owners when login attempts to their sites use compromised credentials. In fact, we use MIGP on the backend for this service to ensure that plaintext credentials never leave the edge server on which they are being processed.
Most standalone credential checking services work by having a user submit a query containing their password’s or username-password pair’s hash prefix. However, this leaks some information to the service, which could be problematic if the service turns out to be malicious or is compromised. In a collaboration with researchers at Cornell Tech published at CCS’19, we showed just how damaging this leaked information can be. Malevolent actors with access to the data shared with most credential checking services can drastically improve the effectiveness of password-guessing attacks. This left open the question: how can you do compromised credential checking without sharing (leaking!) vulnerable credentials to the service provider itself?
What does a privacy-preserving credential checking service look like?
In the aforementioned CCS’19 paper, we proposed an alternative system in which only the hash prefix of the username is exposed to the MIGP server (independent work out of Google and Stanford proposed a similar system). No information about the password leaves the user device, alleviating the risk of password-guessing attacks. These credential checking services help to preserve password secrecy, but still have a limitation: they can only alert users if the exact queried password appears in the breach.
The present evolution of this work, Might I Get Pwned (MIGP), proposes a next-generation similarity-aware compromised credential checking service that supports checking if a password similar to the one queried has been exposed in the data breach. This approach supports the detection of credential tweaking attacks, an advanced version of credential stuffing.
Credential tweaking takes advantage of the fact that many users, when forced to change their password, use simple variants of their original password. Rather than just attempting to log in using an exact leaked password, say ‘password123’, a credential tweaking attacker might also attempt to log in with easily-predictable variants of the password such as ‘password124’ and ‘password123!’.
There are two main mechanisms described in the MIGP paper to add password variant support: client-side generation and server-side precomputation. With client-side generation, the client simply applies a series of transform rules to the password to derive the set of variants (e.g., truncating the last letter or adding a ‘!’ at the end), and runs multiple queries to the MIGP service with each username and password variant pair. The second approach is server-side precomputation, where the server applies the transform rules to generate the password variants when encrypting the dataset, essentially treating the password variants as additional entries in the breach dataset. The MIGP paper describes tradeoffs between the two approaches and techniques for generating variants in more detail. Our demo service includes variant support via server-side precomputation.
Breach extraction attacks and countermeasures
One challenge for credential checking services are breach extraction attacks, in which an adversary attempts to learn username-password pairs that are present in the breach dataset (which might not be publicly available) so that they can attempt to use them in future credential stuffing or tweaking attacks. Similarity-aware credential checking services like MIGP can make these attacks more effective, since adversaries can potentially check for more breached credentials per API query. Fortunately, additional measures can be incorporated into the protocol to help counteract these attacks. For example, if it is problematic to leak the number of ciphertexts in a given bucket, dummy entries and padding can be employed, or an alternative length-hiding bucket format can be used. Slow hashing and API rate limiting are other common countermeasures that credential checking services can deploy to slow down breach extraction attacks. For instance, our demo service applies the memory-hard slow hash algorithm scrypt to credentials as part of the key derivation function to slow down these attacks.
Let’s now get into the nitty-gritty of how the MIGP protocol works. For readers not interested in the cryptographic details, feel free to skip to the demo below!
MIGP protocol
There are two parties involved in the MIGP protocol: the client and the server. The server has access to a dataset of plaintext breach entries (username-password pairs), and a secret key used for both the precomputation and the online portions of the protocol. In brief, the client performs some computation over the username and password and sends the result to the server; the server then returns a response that allows the client to determine if their password (or a similar password) is present in the breach dataset.
Full protocol description from the MIGP paper: clients learn if their credentials are in the breach dataset, leaking only the hash prefix of the queried username to the server
Precomputation
At a high level, the MIGP server partitions the breach dataset into buckets based on the hash prefix of the username (the bucket identifier), which is usually 16-20 bits in length.
During the precomputation phase of the MIGP protocol, the server derives password variants, encrypts entries, and stores them in buckets based on the hash prefix of the username
We use server-side precomputation as the variant generation mechanism in our implementation. The server derives one ciphertext for each exact username-password pair in the dataset, and an additional ciphertext per password variant. A bucket consists of the set ciphertexts for all breach entries and variants with the same username hash prefix. For instance, suppose there are n breach entries assigned to a particular bucket. If we compute m variants per entry, counting the original entry as one of the variants, there will be n*m ciphertexts stored in the bucket. This introduces a large expansion in the size of the processed dataset, so in practice it is necessary to limit the number of variants computed per entry. Our demo server stores 10 ciphertexts per breach entry in the input: the exact entry, eight variants (see Appendix A of the MIGP paper), and a special variant for allowing username-only checks.
Each ciphertext is the encryption of a username-password (or password variant) pair along with some associated metadata. The metadata describes whether the entry corresponds to an exact password appearing in the breach, or a variant of a breached password. The server derives a per-entry secret key pad using a key derivation function (KDF) with the username-password pair and server secret as inputs, and uses XOR encryption to derive the entry ciphertext. The bucket format also supports storing optional encrypted metadata, such as the date the breach was discovered.
Input:
  Secret sk       // Server secret key
  String u        // Username
  String w        // Password (or password variant)
  Byte mdFlag     // Metadata flag
  String mdString // Optional metadata string

Output:
  String C        // Ciphertext

function Encrypt(sk, u, w, mdFlag, mdString):
  padHdr=KDF1(u, w, sk)
  padBody=KDF2(u, w, sk)
  zeros=[0] * KEY_CHECK_LEN
  C=XOR(padHdr, zeros || mdFlag) || mdString.length || XOR(padBody, mdString)
The precomputation phase only needs to be done rarely, such as when the MIGP parameters are changed (in which case the entire dataset must be re-processed), or when new breach datasets are added (in which case the new data can be appended to the existing buckets).
Online phase
During the online phase of the MIGP protocol, the client requests a bucket of encrypted breach entries corresponding to the queried username, and with the server’s help derives a key that allows it to decrypt an entry corresponding to the queried credentials
The online phase of the MIGP protocol allows a client to check if a username-password pair (or variant) appears in the server’s breach dataset, while only leaking the hash prefix of the username to the server. The client and server engage in an OPRF protocol message exchange to allow the client to derive the per-entry decryption key, without leaking the username and password to the server, or the server’s secret key to the client. The client then computes the bucket identifier from the queried username and downloads the corresponding bucket of entries from the server. Using the decryption key derived in the previous step, the client scans through the entries in the bucket attempting to decrypt each one. If the decryption succeeds, this signals to the client that their queried credentials (or a variant thereof) are in the server’s dataset. The decrypted metadata flag indicates whether the entry corresponds to the exact password or a password variant.
The MIGP protocol solves many of the shortcomings of existing credential checking services with its solution that avoids leaking any information about the client’s queried password to the server, while also providing a mechanism for checking for similar password compromise. Read on to see the protocol in action!
MIGP demo
As the state of the art in attack methodologies evolve with new techniques such as credential tweaking, so must the defenses. To that end, we’ve collaborated with the designers of the MIGP protocol to prototype and deploy the MIGP protocol within Cloudflare’s infrastructure.
Our MIGP demo server is deployed at migp.cloudflare.com, and runs entirely on top of Cloudflare Workers. We use Workers KV for efficient storage and retrieval of buckets of encrypted breach entries, capping out each bucket size at the current KV value limit of 25MB. In our instantiation, we set the username hash prefix length to 20 bits, so that there are a total of 2^20 (or just over 1 million) buckets.
There are currently two ways to interact with the demo MIGP service: via the browser client at migp.cloudflare.com, or via the Go client included in our open-sourced MIGP library. As shown in the screenshots below, the browser client displays the request from your device and the response from the MIGP service. You should take caution to not input any sensitive credentials in a third-party service (feel free to use the test credentials [email protected] and password1 for the demo).
Keep in mind that “absence of evidence is not evidence of absence”, especially in the context of data breaches. We intend to periodically update the breach datasets used by the service as new public breaches become available, but no breach alerting service will be able to provide 100% accuracy in assuring that your credentials are safe.
See the MIGP demo in action in the attached screenshots. Note that in all cases, the username ([email protected]) and corresponding username prefix hash (000f90f4) remain the same, so the client retrieves the exact same bucket contents from the server each time. However, the blindElement parameter in the client request differs per request, allowing the client to decrypt different bucket elements depending on the queried credentials.
Example query in which the credentials are exposed in the breach datasetExample query in which similar credentials were exposed in the breach datasetExample query in which the username is present in the breach datasetExample query in which the credentials are not found in the dataset
Open-sourced MIGP library
We are open-sourcing our implementation of the MIGP library under the BSD-3 License. The code is written in Go and is available at https://github.com/cloudflare/migp-go. Under the hood, we use Cloudflare’s CIRCL library for OPRF support and Go’s supplementary cryptography library for scrypt support. Check out the repository for instructions on setting up the MIGP client to connect to Cloudflare’s demo MIGP service. Community contributions and feedback are welcome!
Future directions
In this post, we announced our open-sourced implementation and demo deployment of MIGP, a next-generation breach alerting service. Our deployment is intended to lead the way for other credential compromise checking services to migrate to a more privacy-friendly model, but is not itself currently meant for production use. However, we identify several concrete steps that can be taken to improve our service in the future:
Add more breach datasets to the database of precomputed entries
Increase the number of variants in server-side precomputation
Add library support in more programming languages to reach a broader developer base
Hide the number of ciphertexts per bucket by padding with dummy entries
Add support for efficient client-side variant checking by batching API calls to the server
We are excited to share and build upon these ideas with the wider Internet community, and hope that our efforts impact positive change in the password security ecosystem. We are particularly interested in collaborating with stakeholders in the space to develop, test, and deploy next-generation protocols to improve user security and privacy. You can reach us with questions, comments, and research ideas at [email protected]. For those interested in joining our team, please visit our Careers Page.
As Internet users, we all deal with passwords every day. With so many different services, each with their own login systems, we have to somehow keep track of the credentials we use with each of these services. This situation leads some users to delegate credential storage to password managers like LastPass or a browser-based password manager, but this is far from universal. Instead, many people still rely on old-fashioned human memory, which has its limitations — leading to reused passwords and to security problems. This blog post discusses how Cloudflare Research is exploring how to minimize password exposure and thwart password attacks.
The Problem of Password Reuse
Because it’s too difficult to remember many distinct passwords, people often reuse them across different online services. When breached password datasets are leaked online, attackers can take advantage of these to conduct “credential stuffing attacks”. In a credential stuffing attack, an attacker tests breached credentials against multiple online login systems in an attempt to hijack user accounts. These attacks are highly effective because users tend to reuse the same credentials across different websites, and they have quickly become one of the most prevalent types of online guessing attacks. Automated attacks can be run at a large scale, testing out exposed passwords across multiple systems, under the assumption that some of these passwords will unlock accounts somewhere else (if they have been reused). When a data breach is detected, users of that service will likely receive a security notification and will reset that account password. However, if this password was reused elsewhere, they may easily forget that it needs to be changed for those accounts as well.
How can we protect against credential stuffing attacks? There are a number of methods that have been deployed — with varying degrees of success. Password managers address the problem of remembering a strong, unique password for every account, but many users have yet to adopt them. Multi-factor authentication is another potential solution — that is, using another form of authentication in addition to the username/password pair. This can work well, but has limits: for example, such solutions may rely on specialized hardware that not all clients have. Consumer systems are often reluctant to mandate multi-factor authentication, given concerns that people may find it too complicated to use; companies do not want to deploy something that risks impeding the growth of their user base.
Since there is no perfect solution, security researchers continue to try to find improvements. Two different approaches we will discuss in this blog post are hardening password systems using cryptographically secure keys, and detecting the reuse of compromised credentials, so they don’t leave an account open to guessing attacks.
Improved Authentication with PAKEs
Investigating how to securely authenticate a user just using what they can remember has been an important area in secure communication. To this end, the subarea of cryptography known as Password Authenticated Key Exchange (PAKE) came about. PAKEs deal with protocols for establishing cryptographically secure keys where the only source of authentication is a human memorizable (low-entropy, attacker-guessable) password — that is, the “what you know” side of authentication.
Before diving into the details, we’ll provide a high-level overview of the basic problem. Although passwords are typically protected in transit by being sent over HTTPS, servers handle them in plaintext to verify them once they arrive. Handling plaintext passwords increases security risk — for instance, they might get inadvertently logged and exposed. Ideally, the user’s password never gets sent to the server in the first place. This is where PAKEs come in — a means of verifying that the user and server share a password, ideally without revealing information about the password that could help attackers to discover or crack it.
A few words on PAKEs
PAKE protocols let two parties turn a password into a shared key. Each party only gets one guess at the password the other holds. If a user tries to log in to the wrong server with a PAKE, that server will not be able to turn around and impersonate the user. As such, PAKEs guarantee that communication with one of the parties is the only way for an attacker to test their (single) password guess. This may seem like an unneeded level of complexity when we could use already available tools like a key distribution mechanism along with password-over-TLS, but this puts a lot of trust in the service. You may trust a service with learning your password on that service, but what about if you accidentally use a password for a different service when trying to log in? Note the particular risks of a reused password: it is no longer just a secret shared between a user and a single service, but is now a secret shared between a user and multiple services. This therefore increases the password’s privacy sensitivity — a service should not know users’ account login information for other services.
A comparison of shared secrets between passwords over TLS versus PAKEs.With passwords over TLS, a service might learn passwords used on another service. This problem does not arise with PAKEs.
PAKE protocols are built with the assumption that the server isn’t always working in the best interest of the client and, even more, cannot use any kind of public-key infrastructure during login (although it doesn’t hurt to have both!). This precludes the user from sending their plaintext password (or any information that could be used to derive it — in a computational sense) to the server during login.
PAKE protocols have expanded into new territory since the seminal EKE paper of Bellovin and Merritt, where the client and server both remembered a plaintext version of the password. As mentioned above, when the server stores the plaintext password, the client risks having the password logged or leaked. To address this, new protocols were developed, referred to as augmented, verifier-based, or asymmetric PAKEs (aPAKEs), where the server stored a modified version (similar to a hash) of the password instead of the plaintext password. This mirrors the way many of us were taught to store passwords in a database, specifically as a hash of the password with accompanying salt and pepper. However, in these cases, attackers can still use traditional methods of attack such as targeted rainbow tables. To avoid these kinds of attacks, a new kind of PAKE was born, the strong asymmetric PAKE (saPAKE).
OPAQUE was the first saPAKE and it guarantees defense against precomputation by hiding the password dictionary itself! It does this by replacing the noninteractive hash function with an interactive protocol referred to as an Oblivious Pseudorandom Function (OPRF) where one party inputs their “salt”, another inputs their “password”, and only the password-providing party learns the output of the function. The fact that the password-providing party learns nothing (computationally) about the salt prevents offline precomputation by disallowing an attacker from evaluating the function in their head.
Another way to think about the three PAKE paradigms has to do with how each of them treats the password dictionary:
PAKE type
Password Dictionary
Threat Model
PAKE
The password dictionary is public and common to every user.
Without any guessing, the attacker learns the user’s password upon compromise of the server.
aPAKE
Each user gets their own password dictionary; a description of the dictionary (e.g., the “salt”) is leaked to the client when they attempt to log in.
The attacker must perform an independent precomputation for each client they want to attack.
saPAKE (e.g., OPAQUE)
Each user gets their own password dictionary; the server only provides an online interface (the OPRF) to the dictionary.
The adversary must wait until after they compromise the server to run an offline attack on the user’s password1.
OPAQUE also goes one step further and allows the user to perform the password transformation on their own device so that the server doesn’t see the plaintext password during registration either. Cloudflare Research has been involved with OPAQUE for a while now — for instance, you can read about our previous implementation work and demo if you want to learn more.
But OPAQUE is not a panacea: in the event of server compromise, the attacker can learn the salt that the server uses to evaluate the OPRF and can still run the same offline attack that was available in the aPAKE world, although this is now considerably more time-consuming and can be made increasingly difficult through the use of memory-hard hash functions like scrypt. This means that despite our best efforts, when a server is breached, the attacker can eventually come out with a list of plaintext passwords. Indeed, this attack is always inevitable as the attacker can always run the (sa)PAKE protocol in their head acting as both parties to test each password. With this being the case, we still need to take steps to defend against automated password attacks such as credential stuffing attacks and have ways of mitigating them.
Are You Overexposed?
To help detect and respond to credential stuffing, Cloudflare recently rolled out the Exposed Credential Checks feature on the Web Application Firewall (WAF), which can alert the origin if a user’s login credentials have appeared in a recent breach. Historically, compromised credential checking services have allowed users to be proactive against credential stuffing attacks when their username and password appear together in a breach. However, they do not account for recently proposed credential tweaking attacks, in which an attacker tries variants of a breached password, under the assumption that users often use slight modifications of the same password for different accounts, such as “sunshineFB”, “sunshineIG”, and so on. Therefore, compromised credential check services should incorporate methods of checking for credential tweaks.
Under the hood, Cloudflare’s Exposed Credential Checks feature relies on an underlying protocol deemed Might I Get Pwned (MIGP). MIGP uses the bucketization method proposed in Li et al. to avoid sending the plaintext username or password to the server while handling a large breach dataset. After receiving a user’s credentials, MIGP hashes the username and sends a portion of that hash as a “bucket identifier” to the server. The client and server can then perform a private membership test protocol to verify whether the user’s username/password pair appeared in that bucket, without ever having to send plaintext credentials to the server.
Unlike previous compromised credential check services, MIGP also enables credential tweaking checks by augmenting the original breach dataset with a set of password “variants”. For each leaked password, it generates a list of password variants, which are labeled as such to differentiate them from the original leaked password and added to the original dataset. For more information, you can check out the Cloudflare Research blog post detailing our open-source implementation and deployment of the MIGP protocol.
Measuring Credential Compromises
The question remains, just how important are these exposed credential checks for detecting and preventing credential stuffing attacks in practice? To answer this question, the Research Team has initiated a study investigating login requests to our own Cloudflare dashboard. For this study, we are collecting the data logged by Cloudflare’s Exposed Credential Check feature (described above), designed to be privacy-preserving: this check does not reveal a password, but provides a “yes/no” response on whether the submitted credentials appear in our breach dataset. Along with this signal, we are looking at other fields that may be indicative of malicious behavior such as bot score and IP reputation. As this project develops, we plan to cluster the data to find patterns of different types of credential stuffing attacks that we can generalize to form attack fingerprints. We can then feed these fingerprints into the alert logs for the Cloudflare Detection & Response team to see if they provide useful information for the security analysts.
Additionally, we hope to investigate potential post-compromise behavior as it relates to these compromise check fields. After an attacker successfully hijacks an account, they may take a number of actions such as changing the password, revoking all valid access tokens, or setting up a malicious script. By analyzing compromised credential checks along with these signals, we may be able to better differentiate benign from malicious behavior.
Future directions: OPAQUE and MIGP combined
This post has discussed how we’re approaching the problem of preventing credential stuffing attacks from two different angles. Through the deployment and analysis of compromised credential checks, we aim to prevent server compromise by detecting and preventing credential stuffing attacks before they happen. In addition, in the case that a server does get compromised, the wider use of OPAQUE would help address the problem of leaking passwords to an attacker by avoiding the reception and storage of plaintext passwords on the server as well as preventing precomputation attacks.
However, there are still remaining research challenges to address. Notably, the current method for interfacing with MIGP still requires the server to either pass along a plaintext version of the client’s password, or trust the client to honestly communicate with the MIGP service on behalf of the server. If we want to leverage the security guarantees of OPAQUE (or generally an saPAKE) with the analytics and alert system provided by MIGP in a privacy-preserving way, we need additional mechanisms.
At first glance, the privacy-preserving goals of both protocols seem to be perfect matches for each other. Both OPAQUE and MIGP are built upon the idea of replacing the traditional salted password hashes with an OPRF as a way of keeping the client’s plaintext passwords from ever leaving their device. However, both the interfaces for these protocols rely on user-provided inputs which aren’t cryptographically tied to each other. This allows an attacker to provide a false password to MIGP while providing their actual password to the OPAQUE server. Further, the security analysis of both protocols assume that their idealized building blocks are separated in an important way. This isn’t to say that the two protocols are incompatible, and indeed, much of these protocols may be salvaged.
The next stages for password privacy will be an integration of these two protocols such that a server can be made aware of credential stuffing attacks and the patterns of compromised account usage that can protect a server against the compromise of other servers while providing the same privacy guarantees OPAQUE does. Our goal is to allow you to protect yourself from other compromised servers while protecting your clients from compromise of your server. Stay tuned for updates!
We’re always keen to collaborate with others to build more secure systems, and would love to hear from those interested in password research. You can reach us with questions, comments, and research ideas at [email protected]. For those interested in joining our team, please visit our Careers Page.
… 1There are other ways of constructing saPAKE protocols. The curious reader can see this CRYPTO 2019 paper for details.
Seven years ago, Cloudflare made HTTPS availability for any Internet property easy and free with Universal SSL. At the time, few websites — other than those that processed sensitive data like passwords and credit card information — were using HTTPS because of how difficult it was to set up.
However, as we all started using the Internet for more and more private purposes (communication with loved ones, financial transactions, shopping, healthcare, etc.) the need for encryption became apparent. Tools like Firesheep demonstrated how easily attackers could snoop on people using public Wi-Fi networks at coffee shops and airports. The Snowden revelations showed the ease with which governments could listen in on unencrypted communications at scale. We have seen attempts by browser vendors to increase HTTPS adoption such as the recent announcement by Chromium for loading websites on HTTPS by default. Encryption has become a vital part of the modern Internet, not just to keep your information safe, but to keep you safe.
When it was launched, Universal SSL doubled the number of sites on the Internet using HTTPS. We are building on that with SSL/TLS Recommender, a tool that guides you to stronger configurations for the backend connection from Cloudflare to origin servers. Recommender has been available in the SSL/TLS tab of the Cloudflare dashboard since August 2020 for self-serve customers. Over 500,000 zones are currently signed up. As of today, it is available for all customers!
How Cloudflare connects to origin servers
Cloudflare operates as a reverse proxy between clients (“visitors”) and customers’ web servers (“origins”), so that Cloudflare can protect origin sites from attacks and improve site performance. This happens, in part, because visitor requests to websites proxied by Cloudflare are processed by an “edge” server located in a data center close to the client. The edge server either responds directly back to the visitor, if the requested content is cached, or creates a new request to the origin server to retrieve the content.
The backend connection to the origin can be made with an unencrypted HTTP connection or with an HTTPS connection where requests and responses are encrypted using the TLS protocol (historically known as SSL). HTTPS is the secured form of HTTP and should be used whenever possible to avoid leaking information or allowing content tampering by third-party entities. The origin server can further authenticate itself by presenting a valid TLS certificate to prevent active monster-in-the-middle attacks. Such a certificate can be obtained from a certificate authority such as Let’s Encrypt or Cloudflare’s Origin CA. Origins can also set up authenticated origin pull, which ensures that any HTTPS requests outside of Cloudflare will not receive a response from your origin.
Cloudflare Tunnel provides an even more secure option for the connection between Cloudflare and origins. With Tunnel, users run a lightweight daemon on their origin servers that proactively establishes secure and private tunnels to the nearest Cloudflare data centers. With this configuration, users can completely lock down their origin servers to only receive requests routed through Cloudflare. While we encourage customers to set up tunnels if feasible, it’s important to encourage origins with more traditional configurations to adopt the strongest possible security posture.
Detecting HTTPS support
You might wonder, why doesn’t Cloudflare always connect to origin servers with a secure TLS connection? To start, some origin servers have no TLS support at all (for example, certain shared hosting providers and even government sites have been slow adopters) and rely on Cloudflare to ensure that the client request is at least encrypted over the Internet from the browser to Cloudflare’s edge.
Then why don’t we simply probe the origin to determine if TLS is supported? It turns out that many sites only partially support HTTPS, making the problem non-trivial. A single customer site can be served from multiple separate origin servers with differing levels of TLS support. For instance, some sites support HTTPS on their landing page but serve certain resources only over unencrypted HTTP. Further, site content can differ when accessed over HTTP versus HTTPS (for example, http://example.com and https://example.com can return different results).
Such content differences can arise due to misconfiguration on the origin server, accidental mistakes by developers when migrating their servers to HTTPS, or can even be intentional depending on the use case.
A study by researchers at Northeastern University, the Max Planck Institute for Informatics, and the University of Maryland highlights reasons for some of these inconsistencies. They found that 1.5% of surveyed sites had at least one page that was unavailable over HTTPS — despite the protocol being supported on other pages — and 3.7% of sites served different content over HTTP versus HTTPS for at least one page. Thus, always using the most secure TLS setting detected on a particular resource could result in unforeseen side effects and usability issues for the entire site.
We wanted to tackle all such issues and maximize the number of TLS connections to origin servers, but without compromising a website’s functionality and performance.
Cloudflare relies on customers to indicate the level of TLS support at their origins via the zone’s SSL/TLS encryption mode. The following SSL/TLS encryption modes can be configured from the Cloudflare dashboard:
Off indicates that client requests reaching Cloudflare as well as Cloudflare’s requests to the origin server should only use unencrypted HTTP. This option is never recommended, but is still in use by a handful of customers for legacy reasons or testing.
Flexible allows clients to connect to Cloudflare’s edge via HTTPS, but requests to the origin are over HTTP only. This is the most common option for origins that do not support TLS. However, we encourage customers to upgrade their origins to support TLS whenever possible and only use Flexible as a last resort.
Full enables encryption for requests to the origin when clients connect via HTTPS, but Cloudflare does not attempt to validate the certificate. This is useful for origins that have a self-signed or otherwise invalid certificate at the origin, but leaves open the possibility for an active attacker to impersonate the origin server with a fake certificate. Client HTTP requests result in HTTP requests to the origin.
Full (strict) indicates that Cloudflare should validate the origin certificate to fully secure the connection. The origin certificate can either be issued by a public CA or by Cloudflare Origin CA. HTTP requests from clients result in HTTP requests to the origin, exactly the same as in Full mode. We strongly recommend Full (strict) over weaker options if supported by the origin.
Strict (SSL-Only Origin Pull)causes all traffic to the origin to go over HTTPS, even if the client request was HTTP. This differs fromFull (strict)in that HTTP client requests will result in an HTTPS request to the origin, not HTTP. Most customers do not need to use this option, and it is available only to Enterprise customers. The preferred way to ensure that no HTTP requests reach your origin is to enable Always Use HTTPS in conjunction with Full or Full (strict) to redirect visitor HTTP requests to the HTTPS version of the content.
SSL/TLS encryption modes determine how Cloudflare connects to origins
The SSL/TLS encryption mode is a zone-wide setting, meaning that Cloudflare applies the same policy to all subdomains and resources. If required, you can configure this setting more granularly via Page Rules. Misconfiguring this setting can make site resources unavailable. For instance, suppose your website loads certain assets from an HTTP-only subdomain. If you set your zone to Full or Full (strict), you might make these assets unavailable for visitors that request the content over HTTPS, since the HTTP-only subdomain lacks HTTPS support.
Importance of secure origin connections
When an end-user visits a site proxied by Cloudflare, there are two connections to consider: the front-end connection between the visitor and Cloudflare and the back-end connection between Cloudflare and the customer origin server. The front-end connection typically presents the largest attack surface (for example, think of the classic example of an attacker snooping on a coffee shop’s Wi-Fi network), but securing the back-end connection is equally important. While all SSL/TLS encryption modes (except Off) secure the front-end connection, less secure modes leave open the possibility of malicious activity on the backend.
Consider a zone set to Flexible where the origin is connected to the Internet via an untrustworthy ISP. In this case, spyware deployed by the customer’s ISP in an on-path middlebox could inspect the plaintext traffic from Cloudflare to the origin server, potentially resulting in privacy violations or leaks of confidential information. Upgrading the zone to Full or a stronger mode to encrypt traffic to the ISP would help prevent this basic form of snooping.
Similarly, consider a zone set to Full where the origin server is hosted in a shared hosting provider facility. An attacker colocated in the same facility could generate a fake certificate for the origin (since the certificate isn’t validated for Full) and deploy an attack technique such as ARP spoofing to direct traffic intended for the origin server to an attacker-owned machine instead. The attacker could then leverage this setup to inspect and filter traffic intended for the origin, resulting in site breakage or content unavailability. The attacker could even inject malicious JavaScript into the response served to the visitor to carry out other nefarious goals. Deploying a valid Cloudflare-trusted certificate on the origin and configuring the zone to use Full (strict) would prevent Cloudflare from trusting the attacker’s fake certificate in this scenario, preventing the hijack.
Since a secure backend only improves your website security, we strongly encourage setting your zone to the highest possible SSL/TLS encryption mode whenever possible.
Balancing functionality and security
When Universal SSL was launched, Cloudflare’s goal was to get as many sites away from the status quo of HTTP as possible. To accomplish this, Cloudflare provisioned TLS certificates for all customer domains to secure the connection between the browser and the edge. Customer sites that did not already have TLS support were defaulted to Flexible, to preserve existing site functionality. Although Flexible is not recommended for most zones, we continue to support this option as some Cloudflare customers still rely on it for origins that do not yet support TLS. Disabling this option would make these sites unavailable. Currently, the default option for newly onboarded zones is Full if we detect a TLS certificate on the origin zone, and Flexible otherwise.
Further, the SSL/TLS encryption mode configured at the time of zone sign-up can become suboptimal as a site evolves. For example, a zone might switch to a hosting provider that supports origin certificate installation. An origin server that is able to serve all content over TLS should at least be on Full. An origin server that has a valid TLS certificate installed should use Full (strict) to ensure that communication between Cloudflare and the origin server is not susceptible to monster-in-the-middle attacks.
The Research team combined lessons from academia and our engineering efforts to make encryption easy, while ensuring the highest level of security possible for our customers. Because of that goal, we’re proud to introduce SSL/TLS Recommender.
SSL/TLS Recommender
Cloudflare’s mission is to help build a better Internet, and that includes ensuring that requests from visitors to our customers’ sites are as secure as possible. To that end, we began by asking ourselves the following question: how can we detect when a customer is able to use a more secure SSL/TLS encryption mode without impacting site functionality?
To answer this question, we built the SSL/TLS Recommender. Customers can enable Recommender for a zone via the SSL/TLS tab of the Cloudflare dashboard. Using a zone’s currently configured SSL/TLS option as the baseline for expected site functionality, the Recommender performs a series of checks to determine if an upgrade is possible. If so, we email the zone owner with the recommendation. If a zone is currently misconfigured — for example, an HTTP-only origin configured on Full — Recommender will not recommend a downgrade.
The checks that Recommender runs are determined by the site’s currently configured SSL/TLS option.
The simplest check is to determine if a customer can upgrade from Full to Full (strict). In this case, all site resources are already served over HTTPS, so the check comprises a few simple tests of the validity of the TLS certificate for the domain and all subdomains (which can be on separate origin servers).
The check to determine if a customer can upgrade from Off or Flexible to Full is more complex. A site can be upgraded if all resources on the site are available over HTTPS and the content matches when served over HTTP versus HTTPS. Recommender carries out this check as follows:
Crawl customer sites to collect links. For large sites where it is impractical to scan every link, Recommender tests only a subset of links (up to some threshold), leading to a trade-off between performance and potential false positives. Similarly, for sites where the crawl turns up an insufficient number of links, we augment our results with a sample of links from recent visitors requests to the zone to provide a high-confidence recommendation. The crawler uses the user agent Cloudflare-SSLDetector and has been added to Cloudflare’s list of known good bots. Similar to other Cloudflare crawlers, Recommender ignores robots.txt (except for rules explicitly targeting the crawler’s user agent) to avoid negatively impacting the accuracy of the recommendation.
Download the content of each link over both HTTP and HTTPS. Recommender makes only idempotent GET requests when scanning origin servers to avoid modifying server resource state.
Run a content similarity algorithm to determine if the content matches. The algorithm is adapted from a research paper called “A Deeper Look at Web Content Availability and Consistency over HTTP/S” (TMA Conference 2020) and is designed to provide an accurate similarity score even for sites with dynamic content.
Recommender is conservative with recommendations, erring on the side of maintaining current site functionality rather than risking breakage and usability issues. If a zone is non-functional, the zone owner blocks all types of bots, or if misconfigured SSL-specific Page Rules are applied to the zone, then Recommender will not be able to complete its scans and provide a recommendation. Therefore, it is not intended to resolve issues with website or domain functionality, but rather maximize your zone’s security when possible.
Please send questions and feedback to [email protected]. We’re excited to continue this line of work to improve the security of customer origins!
Mentions
While this work is led by the Research team, we have been extremely privileged to get support from all across the company!
Special thanks to the incredible team of interns that contributed to SSL/TLS Recommender. Suleman Ahmad (now full-time), Talha Paracha, and Ananya Ghose built the current iteration of the project and Matthew Bernhard helped to lay the groundwork in a previous iteration of the project.
Today, we are announcing the general availability of Cloudflare Waiting Room to customers on our Enterprise plans, making it easier than ever to protect your website against traffic spikes. We are also excited to present several new features that have user experience in mind — an alternative queueing method and support for custom web/mobile applications.
First-In-First-Out (FIFO) Queueing
Whether you’ve waited to check out at a supermarket or stood in line at a bank, you’ve undoubtedly experienced FIFO queueing. FIFO stands for First-In-First-Out, which simply means that people are seen in the order they arrive — i.e., those who arrive first are processed before those who arrive later.
When Waiting Room was introduced earlier this year, it was first deployed to protect COVID-19 vaccine distributors from overwhelming demand — a service we offer free of charge under Project Fair Shot. At the time, FIFO queueing was the natural option due to its wide acceptance in day-to-day life and accurate estimated wait times. One problem with FIFO is that users who arrive later could see long estimated wait times and decide to abandon the website.
We take customer feedback seriously and improve products based on it. A frequent request was to handle users irrespective of the time they arrive in the Waiting Room. In response, we developed an additional approach: random queueing.
A New Approach to Fairness: Random Queueing
You can think of random queueing as participating in a raffle for a prize. In a raffle, people obtain tickets and put them into a big container. Later, tickets are drawn at random to determine the winners. The more time you spend in the raffle, the better your chances of winning at least once, since there will be fewer tickets in the container. No matter what, everyone participating in the raffle has an opportunity to win.
Similarly, in a random queue, users are selected from the Waiting Room at random, regardless of their initial arrival time. This means that you could be let into the application before someone who arrived earlier than you, or vice versa. Just like how you can buy more tickets in a raffle, joining a random queue earlier than someone else will give you more attempts to be accepted, but does not guarantee you will be let in. However, at any particular time, you will have the same chance to be let into the website as anyone else. This is different from a raffle, where you could have more tickets than someone else at a given time, providing you with an advantage.
Random queueing is designed to give everyone a fair chance. Imagine waking up excited to purchase new limited-edition sneakers only to find that the FIFO queue is five hours long and full of users that either woke up in the middle of the night to get in line or joined from earlier time zones. Even if you waited five hours, those sneakers would likely be sold out by the time you reach the website. In this case, you’d probably abandon the Waiting Room completely and do something else. On the other hand, if you were aware that the queue was random, you’d likely stick around. After all, you have a chance to be accepted and make a purchase!
As a result, random queueing is perfect for short-lived scenarios with lots of hype, such as product launches, holiday traffic, special events, and limited-time sales.
By contrast, when the event ends and traffic returns to normal, a FIFO queue is likely more suitable, since its widely accepted structure and accurate estimated wait times provide a consistent user experience.
How Does Random Queueing Work?
Perhaps the best part about random queueing is that it maintains the same internal structure that powers FIFO. As a result, if you change the queueing method in the dashboard — even when you may be actively queueing users — the transition to the new method is seamless. Imagine you have users 1, 2, 3, 4, and 5 waiting in a FIFO queue in the order 5 → 4 → 3 → 2 → 1, where user 1 will be the next user to access the application. Let’s assume you switch to random queueing. Now, any user can be accepted next. Let’s assume user 4 is accepted. If you decide to immediately switch back to FIFO queueing, the queue will reflect the order 5 → 3 → 2 → 1. In other words, transitioning from FIFO to random and back to FIFO will respect the initial queue positions of the users! But how does this work? To understand, we first need to remember how we built Waiting Room for FIFO.
Recall the Waiting Room configurations:
Total Active Users. The total number of active users that can be using the application at any given time.
New Users Per Minute.The maximum number of new users per minute that can be accepted to the application.
Next, remember that Waiting Room is powered by cookies. When you join the Waiting Room for the first time, you are assigned an encrypted cookie. You bring this cookie back to the Waiting Room and update it with every request, using it to prove your initial arrival time and status.
Properties in the Waiting Room cookie include:
bucketId. The timestamp rounded down to the nearest minute of the user’s first request to the Waiting Room. If you arrive at 10:23:45, you will be grouped into a bucket for 10:23:00.
acceptedAt. The timestamp when the user got accepted to the origin website for the first time.
refreshIntervalSeconds. When queueing, this is the number of seconds the user must wait before sending another request to the Waiting Room.
lastCheckInTime. The last time each user checked into the Waiting Room or origin website. When queueing, this is only updated for requests every refreshIntervalSeconds.
For any given minute, we can calculate the number of users we can let into the origin website. Let’s say we deploy a Waiting Room on “https://example.com/waitingroom” that can support 10,000 Total Active Users, and we allow up to 2,000 New Users Per Minute. If there are currently 7,000 active users on the website, we have 10,000 – 7,000 = 3,000 open slots. However, we need to take the minimum (3,000, 2,000) = 2,000 since we need to respect the New Users Per Minute limit. Thus, we have 2,000 available slots we can give out.
Let’s assume there are 2,500 queued users that joined over the last three minutes in groups of 500, 1,000, and 1,000, respectively for the timestamps 15:54, 15:55, and 15:56. To respect FIFO queueing, we will take our 2,000 available slots and try to reserve them for users who joined first. Thus, we will reserve 500 available slots for the users who joined at 15:54 and then reserve 1000 available slots for the users who joined at 15:55. When we get to the users for 15:56, we see that we only have 500 slots left, which is not enough for the 1,000 queued users for this minute:
Since we have reserved slots for all users with bucketIds of 15:54 and 15:55, they can be let into the origin website from any data center. However, we can only let in a subset of the users who initially arrived at 15:56.
Timestamp (bucketId)
Queued Users
Reserved Slots
Strategy
15:54
500
500
Accept all users
15:55
1,000
1,000
Accept all users
15:56
1,000
500
Accept subset of users
These 500 slots for 15:56 are allocated to each Cloudflare edge data center based on its respective historical traffic data, and further divided for each Cloudflare Worker within the data center. For example, let’s assume there are two data centers — Nairobi and Dublin — which share 60% and 40% of the traffic, respectively, for this minute. In this case, we will allocate 500 * .6 = 300 slots for Nairobi and 500 * .4 = 200 slots for Dublin. In Nairobi, let’s say there are 3 active workers, so we will grant each of them 300 / 3 = 100 slots. If you make a request to a worker in Nairobi and your bucketId is 15:56, you will be allowed in and consume a slot if the worker still has at least one of its 100 slots available. Since we have reserved all 2,000 available slots, users with bucketIds after 15:56 will have to continue queueing.
Let’s modify this case and assume we only have 200 queued users, all of which are in the 15:54 bucket. First, we reserve 200 slots for these queued users, leaving us 2,000 – 200 = 1,800 remaining slots. Since we have reserved slots for all queued users, we can use the remaining 1,800 slots on new users — people who have just made their first request to the Waiting Room and don’t have a cookie or bucketId yet. Similar to how we handle buckets with fewer slots than queued users, we will distribute these 1,800 slots to each data center, allocating 1,800 * .6 = 1,080 to Nairobi and 1,800 * .4 = 720 to Dublin. In Nairobi, we will split these equally across the 3 workers, giving them 1,080 / 3 = 360 slots each. If you are a new user making a request to a worker in Nairobi, you will be accepted and take a slot if the worker has at least one of its 360 slots available, otherwise you will be marked as a queued user and enter the Waiting Room.
Now that we have outlined the concepts for FIFO, we can understand how random queueing operates. Simply put, random queueing functions the same way as FIFO, except we pretend that every user is new. In other words, we will not look at reserved slots when making the decision if the user should be let in. Let’s revisit the last case with 200 queued users in the 15:54 bucket and 2,000 available slots. When random queueing, we allocate the full 2,000 slots to new users, meaning Nairobi gets 2,000 * .6 = 1,200 slots and each of its 3 workers gets 1,200 / 3 = 400 slots. No matter how many users are queued or freshly joining the Waiting Room, all of them will have a chance at taking these slots.
Finally, let’s reiterate that we are only pretending that all users are new — we still assign them to bucketIds and reserve slots as if we were FIFO queueing, but simply don’t make any use of this logic while random queueing is active. That way, we can maintain the same FIFO structure while we are random queueing so that if necessary, we can smoothly transition back to FIFO queueing and respect initial user arrival times.
How “Random” is Random Queueing?
Since random queueing is basically a race for available slots, we were concerned that it could be exploited if the available user slots and the queued user check-ins did not occur randomly.
To ensure all queued users can attempt to get into the website at the same rate, we store (in the encrypted cookie) the last time each user checked into the Waiting Room (lastCheckInTime) to prevent them from attempting to gain access to the website until a number of seconds have passed (refreshIntervalSeconds). This means that spamming the page refresh button will not give you an advantage over other queued users! Be patient — the browser will refresh automatically the moment you are eligible for another chance.
Next, let’s imagine five queued users checking into the Waiting Room every refreshIntervalSeconds=30 at approximately the :00 and :30 minute marks. A new queued user joins the Waiting Room and checks in at approximately :15 and :45. If new slots are randomly released, this new user will have about a 50% chance of being selected next, since it monopolizes over the :00-15 and :30-45 ranges. On the other hand, the other five queued users share the :15-30 and :45-00 ranges, giving them about a 50% / 5 = 10% chance each. Let’s consider that new slots are not randomly released and assume they are always released at :59. In this case, the new queued user will have virtually no chance to be selected before the other five queued users because these users will always check in one second later at :00, immediately consuming any newly released slots.
To address this vulnerability, we changed our implementation to ensure that slots are released randomly and encouraged users to check in at random offsets from each other. To help split up users that are checking in at similar times, we vary each user’s refreshIntervalSeconds by a small, pseudo-randomly generated offset for each check-in and store this new refresh interval in the encrypted Waiting Room cookie for validation on the next request. Thus, a user who previously checked in every 30 seconds might now check in after 29 seconds, then 31 seconds, then 27 seconds, and so on — but still averaging a 30-second refresh interval. Over time, these slight check-in variations become significant, spreading out user check-in times and strengthening the randomness of the queue. If you are curious to learn more about the apparent “randomness” behind mixing user check-in intervals, you can think of it as a chaotic system subjected to the butterfly effect.
Nevertheless, we weren’t convinced our efforts were enough and wanted to test random queueing empirically to validate its integrity. We conducted a simulation of 10,000 users joining a Waiting Room uniformly across 30 minutes. When let into the application, users spent approximately 1 minute “browsing” before they stopped checking in. We ran this experiment for both FIFO and random queueing and graphed each user’s observed wait time in seconds in the Waiting Room against the minute they initially arrived (starting from 0). Recall that users are grouped by minute using bucketIds, so each user’s arrival minute is truncated down to the current minute.
Based on our data, we can see immediately for FIFO queueing that, as the arrival minute increases, the observed wait time increases linearly. This makes sense for a FIFO queue, since the “line” will just get longer if there are more users entering the queue than leaving it. For each arrival minute, there is very little variation among user wait times, meaning that if you and your friend join a Waiting Room at approximately the same time, you will both be accepted around the same time. If you join a couple of minutes before your friend, you will almost always be accepted first.
When looking at the results for random queueing, we observe users experiencing varied wait times regardless of the arrival minute. This is expected, and helps prove the “randomness” of the random queue! We can see that, if you join five minutes after your friend, although your friend will have more chances to get in, you may still be accepted first! However, there are so many data points overlapping with each other in the plot that it is hard to tell how they are distributed. For instance, it could be possible that most of these data points experience extreme wait times, but as humans we aren’t able to tell.
import json
import numpy as np
import matplotlib.pyplot as plt
import sys

filename = sys.argv[1]

with open(filename) as file:
   data = json.load(file)

   x = data["ArrivalMinutes"]
   y = data["WaitTimeSeconds"]

   heatmap, _, _ = np.histogram2d(x, y, bins=(30, 30))

   plt.clf()
   plt.title(filename)
   plt.xlabel('Arrival Minute Buckets')
   plt.ylabel('WaitTime Buckets')
   plt.imshow(heatmap.T, origin='lower')
   plt.show()
The heatmaps display where the data points are concentrated in the original plot, using brighter (hotter) colors to represent areas containing more points:
By inspecting the generated heatmaps, we can conclude that FIFO and random queueing are working properly. For FIFO queueing, users are being accepted in the order they arrive. For random queueing, we can see that users are accepted to the origin regardless of arrival time. Overall, we can see the heatmap for random queueing is well distributed, indicating it is sufficiently random!
If you are curious why random queueing has very hot colors along the lowest wait times followed by very dark colors afterward, it is actually because of how we are simulating the queue. For the simulation, we spoofed the bucketIds of the users and let them all join the Waiting Room at once to see who would be let in first. In the random queueing heatmap, the bright colors along the lowest wait time buckets indicate that many users were accepted quickly after joining the queue across all bucketIds. This is expected, demonstrating that random queueing does not give an edge to users who join earlier, giving each user a fair chance regardless of its bucketId. The reason why these users were almost immediately accepted in WaitTime Bucket 0 is because this simulation started with no users on the origin, meaning new users would be accepted until the Waiting Room limits were reached. Since this first wave of accepted users “browsed” on the origin for a minute before leaving, no additional users during this time were let in. Thus, the colors are very dark for WaitTime Buckets 1 and 2. Similarly, the second wave of users is randomly selected afterward, followed by another period of time when no users were accepted in WaitTime Bucket 5. As the wait time increases, the more attempts a particular user will have to be let in, meaning it is unlikely for users to have extreme wait times. We can see this by observing the colors grow darker as the WaitTime Bucket approaches 29.
How Is Estimated Time Calculated for Random Queueing?
In a random queue, you can be accepted at any moment… so how can you display an estimated wait time? For a particular user, this is an impossible task, but when you observe all the users together, you can accurately account for most user experiences using a probabilistic estimated wait time range.
At any given moment, we know:
letInPerMinute. The current average users per minute being let into the origin.
currentlyWaiting. The current number of users waiting in the queue.
Therefore, we can calculate the probability of a user being let into the origin in the next minute:
If there are 100 users waiting in the queue, and we are currently letting in 10 users per minute, the probability a user will be let in over the next minute is 10 / 100 = .1 (10%).
Using P(LetInOverMinute), we can determine the n minutes needed for a p chance of being let into the origin:
p = 1 – (1 – P(LetInOverMinute))n
Recall that the probability of getting in at least once is the complement of not getting in at all. The probability of not being let into the origin over n minutes is (1 – P(LetInOverMinutes))n. Therefore, the probability of getting in at least once is 1 – (1 – P(LetInOverMinute))n. This equation can be simplified further:
n = log(1 – p) / log(1 – P(LetInOverMinute))
Thus, if we want to calculate the estimated wait time to have a p = .5 (50%) chance of getting into the origin with the probability of getting let in during a particular minute P(LetInOverMinute) = .1 (10%), we calculate:
n = log(1 – .5) / log(1 – .1) ≈ 6.58 minutes or 6 minutes and 35 seconds
In this case, we estimate that 50% of users will wait less than 6 minutes and 35 seconds and the remaining 50% of users will wait longer than this.
So, which estimated wait times are displayed to the user? It is up to you! If you create a Mustache HTML template for a Waiting Room, you will now be able to use the variables waitTime25Percentile, waitTime50Percentile, and waitTime75Percentile to display the estimated wait times in minutes when p = .25, p = .5, and p = .75, respectively. There are also new variables that are used to display and determine the queueing method, such as queueingMethod, isFIFOQueue, and isRandomQueue. If you want to display something more dynamic like a custom view in a mobile app, keep reading to learn about our new JSON response, which provides a REST API for the same set of variables.
Supporting Dynamic Applications with a JSON Response
Before, customers could only deploy static Mustache HTML templates to customize the style of their Waiting Rooms. These templates work well for most use cases, but fall short if you want to display anything that requires state. Let’s imagine you’re queueing to buy concert tickets on your mobile device, and you see an embedded video of your favorite song. Naturally, you click on it and start singing along! A couple seconds later, the browser refreshes the page automatically to update your status in the Waiting Room, resetting your video to the start.
The purpose of the new JSON response is to give full control to a custom application, allowing it to determine what to display to the user and when to refresh. As a result, the application can maintain state and make sure your videos are never interrupted again!
Once the JSON response is enabled for a Waiting Room, any request to the Waiting Room with the header Accept: application/json will receive a JSON object with all the fields from the Mustache template.
An example request when the queueing method is FIFO:
Don’t forget that Waiting Room uses a cookie to maintain a user’s status! Without a cookie in the request, the Waiting Room will think the user has just joined the queue.
Don’t forget to refresh! Inspect the ‘Refresh’ HTTP response header or the refreshIntervalSeconds property and send another request to the Waiting Room after that number of seconds.
Keep in mind that if the user’s request is let into the origin, JSON may not necessarily be returned. To gracefully parse all responses, send JSON from the origin website if the header Accept: application/json is present. For example, the origin could return:
SameSite and Secure are attributes in the HTTP response Set-Cookie header. SameSite is used to determine when cookies are sent to a website while Secure indicates if there must be a secure context (HTTPS).
There are three different values of SameSite:
SameSite=Lax.This is the default value when the SameSite attribute is not present. Cookies are not sent on cross-site sub-requests unless the user is following a link to the third-party site. If you are on example1.com, cookies will not be sent to example2.com unless you click a link that navigates to example2.com.
SameSite=Strict. Cookies are sent only in first-party contexts. If you are on example1.com, cookies will never be sent to example2.com even if you click a link that navigates to example2.com.
SameSite=None. Cookies are sent for all contexts, but the Secure attribute must be set. If you are on example1.com, cookies will be sent to example2.com for all sub-requests. If Secure is not set, the browser will block the cookie.
IFrames (Inline Frames) allow HTML documents to embed other HTML documents, such as an advertisement, video, or webpage. When an application from a third-party website is rendered inside an IFrame, cookies will only be sent to it if SameSite=None is set.
Why is this all important? In the past, we did not set SameSite, meaning it defaulted to SameSite=Lax for all responses. As a result, a user queueing through an IFrame would never have its cookie updated and appear to the Waiting Room as joining for the first time on every request. Today, we are introducing customization for both the SameSite and Secure attributes, which will allow Waiting Rooms to be displayed in IFrames!
At the moment, this is only configurable through the Cloudflare API. By default, the configuration for SameSite and Secure will be set to “auto”, automatically selecting the most flexible option. In this case, SameSite will be set to None if Always Use HTTPS is enabled, otherwise it will be set to Lax. Similarly, Secure will only be set if Always Use HTTPS is enabled. In other words, Waiting Room IFrames will work properly by default as long as Always Use HTTPS is toggled. If you are wondering why Always Use HTTPS is used here, remember that SameSite=None requires that Secure is also set, or else the browser will block the Waiting Room cookie.
If you decide to manually configure the behavior of SameSite and Secure through the API, be careful! We do guard against setting SameSite=None without Secure, but if you decide to set Secure on every request (secure=”always”) and don’t have Always Use HTTPS enabled, this means that a user who sends an insecure (HTTP) request to the Waiting Room will have its cookie blocked by its browser!
If you want to explore using IFrames with Waiting Room yourself, here is a simple example of a Cloudflare Worker that renders the Waiting Room on “https://example.com/waitingroom” in an IFrame:
Waiting Room still has plenty of room to grow! Every day, we are seeing more Waiting Rooms deployed to protect websites from traffic spikes. As Waiting Room continues to be used for new purposes, we will keep adding features to make it as customizable and user-friendly as possible.
Stay tuned — what we have announced today is just the tip of the iceberg of what we have planned for Waiting Room!
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.