Announcing Cloudflare K2: serverless event streams

Post Syndicated from Micah Wylde original https://blog.cloudflare.com/cloudflare-k2-streams/

With traditional Remote Procedure Call (RPC) architectures, there exists a core challenge: producers and consumers must align in scale and in time. If your producers send too much data for your consumers to handle or if your consumers or downstream services become unavailable, events are dropped. This problem is compounded with multiple consumers that need to independently process the data. For example, an ecommerce backend may emit events when transactions are completed, which need to be read by an analytics system and a fraud detection service.

We can solve this by decoupling our producers and consumers — inserting a service in the middle that absorbs writes while allowing independent readers to consume at their own pace.

Today we are launching Cloudflare K2 in public beta to solve this problem. K2 is a durable event streaming primitive on the Developer Platform. You send events to a K2 stream, which stores them as an ordered log. Consumers can read them in a variety of ways, for example by splitting up reads across a set of consumers, or delivering all messages to all consumers. It's fully serverless, scales to vast quantities of data, and supports long-term retention, so even long periods of consumer downtime do not lose data.

Under the hood, K2 implements a partitioned, durable log on top of R2 object storage, which allows it to scale to huge volumes of storage.

If you’re ready to get started, you can create your first stream in seconds by following the guide here.

Streams on the edge

We first built K2 because we needed a durable buffer on the edge, initially to serve as the ingestion layer for Basin Pipelines. Pipelines is powered by a stream processing engine that operates on a pull-based model, which means some other system has to store events before they are read, transformed, and written to R2. And because we commit to never dropping events once they’re accepted into the Pipelines Stream, that storage has to be durable — meaning it can’t lose data — over potentially long periods of time.

This is where most companies would deploy Apache Kafka. However, Pipelines runs on the Cloudflare edge, which spans a huge number of servers across over 335 cities. Our unique architecture means we often cannot run traditional distributed systems software like Kafka, and need to rethink how these systems are built and operated.

For stateful services, in particular, Cloudflare’s global infrastructure presents some challenges: we get relatively small slices of machines, those machines are relatively ephemeral, and networking is often over the public Internet. But our infrastructure also has a few superpowers: it’s close to users wherever they are in the world and has an incredible capacity to scale horizontally.

In designing the durable buffering system that became K2, we decided to rely on the powerful state primitive we already have: R2. Object storage systems like R2 combine extremely durable storage (11 9s!) with strongly consistent APIs. Offloading replication and consensus to the storage layer allows us to make the application layer (K2 in this case) radically simpler, cheaper, and higher performance. A secondary benefit is that it separates compute and storage, meaning each can be scaled independently. This allows us to store vast quantities of historical data at low cost.

How do we build a log on top of object storage? An immediate issue is that R2 — like other object stores — does not support appends, the standard operation on a log. Instead, we must write complete files, or segments, that are large enough to overcome the cost of writing and reading each one. We do this by first accumulating writes in-memory on an edge service. After waiting a short period for data to arrive, we write all events as a segment file. We achieve ordering and strictly incrementing offsets using R2’s atomic operations without needing a separate coordination service.

While building on R2 has many advantages, there is one downside: higher produce latencies. Writing to object storage is slower than a local disk, and we have to wait for the local batch to accumulate before starting the write. In our initial release of K2, this adds up to about 1 second of produce latency at the 99th percentile of response times.

We will be sharing more details on the design of K2 in an upcoming technical deep dive.

Streams, Queues, or Pipelines?

Cloudflare has several existing asynchronous delivery primitives, including Queues and Basin Pipelines. When should you reach for K2 instead of these existing products?

There are some superficial similarities between Queues and K2 Streams: both receive events, durably store them, and deliver them to consumers. Queues are designed around tracking individual items of expensive or time consuming work that need to be asynchronously completed. For example, an image processing application may enqueue a user request to be handled by the actual image processing service. They support complex logic on the grain of a particular work item, like retries, delays, and dead-letter queues for failed attempts.

K2, by contrast, is designed for high-scale data movement, long-term retention, and fan-out consumption. Messages are produced and consumed as batches — enabling efficient processing at the expense of message-level retries. This batching also drives higher producer latency than for queues.

Basin Pipelines is a serverless ingestion service. You can send your Pipeline JSON events, which can be transformed and written to R2 or a Basin Catalog. We recommend Pipelines when the end result is writing your events to object storage or Iceberg tables, and K2 when doing custom processing or writing to other destinations.

Getting started

Using K2 involves first creating a stream. You can have many streams across your account for different use cases or types of events. Streams can be created via cf, Wrangler, the dashboard, or API.

Let's take the example of collecting and processing product analytics. First, we'll create a stream with cf:

Once we have a stream, we can start producing to it, via an HTTP API or Worker binding. For example, from a Worker:

K2 represents data as bytes, so you can use whatever format or encoding makes sense for your application.

Now that we have events in a stream, we can create a subscription. Subscriptions divide up work between consumers, enabling read parallelism — scaling out to multiple readers to handle more load than a single server can manage.

We can create a subscription via the HTTP API.

With the subscription created, we can then poll it from each of our consumers:

When a client calls consume, they receive a lease for that particular batch of events for 5 minutes. The client can do one of three things:

  • ack the batch, which marks it as processed and ensures it will not be redelivered
  • nack (negative ack) it, meaning we’ve failed to process it and would like it to be redelivered
  • extend its lease, in case it needs more time to complete processing

This is one way to consume from K2: splitting work amongst multiple consumers such that each consumer gets a portion of the data. Another way to read is with a separate subscription for each consumer — the pub/sub pattern — in which case each consumer sees all of the messages. Or you can mix-and-match between these two approaches, having multiple independent consumer pools.

See the K2 docs for full details on the APIs.

Pricing and Availability

K2 is available today in public beta for accounts with Workers Paid subscriptions, within these limits:

  • Maximum of 10GB of storage used
  • 30 MB/s produce per stream

If you need higher limits, please reach out to the team on Discord or fill out the limit increase form.

Usage of K2 will not be billed during the beta period. Once we begin billing, we anticipate this pricing:

Pricing

Data Produced

$0.04 / GB

Data Consumed

$0.04 / GB

Data Retained

$0.02 / GB / month

What’s next

We have an exciting roadmap for K2 over the coming months, including:

  • Higher write parallelism, up to multi-GB/s streams
  • Message keys and key-based ordering guarantees
  • Push-based worker consumers
  • Express tier with lower produce and end-to-end latencies
  • Drop-in support for Apache Kafka clients

We’re excited to see what you build on K2! Share your feedback on the Cloudflare Discord.

We want you to build the next Git platform on Cloudflare

Post Syndicated from Dina Kozlov original https://blog.cloudflare.com/next-git-platform-on-cloudflare/

GitHub was built for a world where humans write code, organize it into repositories, and collaborate through branches, commits, issues, and pull requests.

But the next generation of software is going to be built differently because it is going to be built by a different kind of developer: agents.

Agents are already writing more code than ever before — they’re fixing bugs, building features, writing tests, reviewing changes, updating dependencies, and doing the routine maintenance required to keep an application running.

So in this new world where you have hundreds, or even thousands, of agents working on the same codebase at the same time, what does the foundation look like?

How do agents know what other agents are working on? What happens when they make conflicting changes? How do you review everything they produce? How do you keep track of not just what changed, but why a change was made?

And so the burning question is: What does the next GitHub look like?

We want you to help us answer it, by building it out.

Earlier this year, we launched Artifacts, a versioned filesystem that speaks Git and can scale to millions of repositories. From the start, we designed Artifacts as a set of programmable primitives that developers could use to build their own products, workflows, and abstractions.

Artifacts provides the foundation: repositories that can be created and forked programmatically, versioned storage for code and agent context, and the Git operations agents already know how to use.

With that foundation in place, you can focus on the layer above it: how agents coordinate their work, how changes are reviewed and merged, and what the developer experience should look like when hundreds or thousands of agents are working on the same codebase.

That is the layer we want you to build.

Now that Artifacts is in open beta, we’re holding a competition to see who can build the next Git platform on Cloudflare using Workers and Artifacts.

Artifacts is in open beta. Here’s why you should build on it

When we launched Artifacts, our goal was to make it possible to create a repository for every agent, session, task, or user — and to do that at the scale agents require.

Since then, we’ve seen developers use Artifacts in a range of ways: Vibe-coding platforms are using it to store the projects their users create. Developers are using it to persist the code and context from agent sessions. Others are creating isolated repositories, so multiple agents can safely work from the same starting point and compare or merge the results later.

Here are some new capabilities we’ve added since the initial launch.

Deploy Artifacts repos to Workers

You can now connect an Artifacts repository to a Worker through Workers Builds. When you or an agent pushes code to the Artifacts repository, Cloudflare will build the project and, for the production branch, deploy the updated Worker. Pushes to other branches automatically create or update Workers Previews, giving you an isolated, shareable version of your Worker where you can test changes before they go live.

You can connect an existing Worker to an Artifacts repository or start a new project and automatically store it in Artifacts.

Manage Artifacts directly from Workers

You can interact with Artifacts repositories directly from a Worker using an Artifacts binding to create or fork repos, inspect files and commits, and issue repo-scoped Git tokens. This makes your Git workflow programmable. When a new task arrives, a Worker can fork the project for an agent, read the files it needs for context, and give it a repository to work in. When the agent pushes a change, your automation can inspect the result and start a review. You define those steps in code to fit how your agents work.

For example, here’s how to fork a project for a new agent task and read its AGENTS.md for instructions:

React to every change with event subscriptions

Artifacts publishes events whenever a repository is created, imported, forked, deleted, pushed to, cloned, or fetched. You can subscribe to these events to decide what happens next: run CI, kick off a code review agent, or deploy a change.

For example, you can subscribe to Artifacts push events and have a Worker start a code review workflow for each push. The Worker passes the repository, branch, and new commit to the Workflow, giving a review agent the context it needs to inspect the change:

Data jurisdiction for Artifacts repos

You can now choose where Artifacts stores and processes your repository data. Set a U.S. or EU jurisdiction when you create a namespace, and every repository created in that namespace will automatically follow the same restriction.

View Artifacts metrics

You can now see metrics for your Artifacts repositories in the Cloudflare dashboard. For each repository, you can now see total operations, pulls, pushes, errors, and error rate, helping you understand how the repository is being used and spot failures. You can also query Artifacts metrics directly to build your own dashboards or monitoring.

Pricing

Artifacts pricing is based on repository operations and the amount of data stored. We will begin billing for Artifacts usage on October 15, 2026.

Competition: Build the next Git platform on Cloudflare

We want you to build your vision for the Git platform of the agentic era using Cloudflare Workers and Artifacts.

You could rethink repositories, branches, pull requests, worktrees, code review, and merge conflicts — or build new ways to preserve agent context, compare multiple changes at the same time, and decide which one should ship.

We aren’t looking for GitHub as it exists today with agents added on top. At a minimum, we want to see multiple agents working on changes concurrently. Beyond that, we want you to get creative — what you think comes next.

How to enter

Submit:

  • A 5-10 minute video demonstrating what you built, what it enables agents and developers to do, and how it works
  • A link to the source code, which must be provided under a permissive open source license (MIT, Apache, BSD)
  • Instructions for running or trying the project

Deadline

Submissions are open until October 14, 2026.

Why should you participate?

We’ll select the top three projects and fly up to two members from each team to San Francisco to attend Cloudflare Connect and show what they built.

The first-place team will also receive $25,000 in Cloudflare credits, along with invitations to the VIP speaker dinner on Monday night at Connect.

Get started

Artifacts is available in open beta to customers on the Workers Paid plan.

Get started with your coding agent: copy the prompt below to set up your first Artifacts repository and start pushing code to it.

You can view or create the Artifacts repositories in the dashboard or if you’re looking to learn more, check out the documentation.

AI Search is now generally available

Post Syndicated from Gabriel Massadas original https://blog.cloudflare.com/ai-search-ga/

Cloudflare’s AI Search combines Workers AI, Vectorize, R2, and Browser Run into a fully managed index and retrieval pipeline. Since we launched AI Search over a year ago, we’ve seen developers use it to power a wide range of search use cases, from searching internal documentation to powering search for their websites. We use AI Search ourselves to power search on our own blog and developer docs.

Starting today, AI Search is generally available. And as part of it, we've expanded and improved our support for multimodal formats beyond text, adding native image embeddings, optical character recognition (OCR) for PDFs, and support for larger files.

As part of general availability, we’ll start billing for AI Search on November 1, 2026, and continue to offer a generous free tier on all Workers plans.

New: multimodal embedding and retrieval

An image is more than the sentence used to describe it. Product texture, screenshot state, chart relationships, document layout, and fine visual detail can all disappear when pixels are compressed into a caption.

AI Search now preserves both signals: it embeds image pixels directly for visual retrieval while retaining captions for textual understanding. To keep these richer representations efficient, AI Search leverages Matryoshka Representation Learning (MRL), allowing smaller embeddings to retain useful information while keeping storage manageable and search fast.

Although we originally supported retrieval over images, the implementation was naive: we would perform object detection, generate a caption, and then embed that text. This made images searchable, but only through the details captured in the caption. Now, we do both — caption-based understanding and native image retrieval.

Native multimodal retrieval is available today with the Qwen3-VL-Embedding model. At query time, AI Search checks whether your instance’s embedding model supports images. If it does, a query image is embedded directly by that model, landing in the same vector space as your indexed images and text.

If your embedding model is text-only, you can still query with an image. AI Search converts the query image to text with ToMarkdown and searches using the resulting caption. This gives every model basic multimodal support, while models with native image support get the full visual signal.

Caption-based understanding

A small bird with black-and-white markings perched among golden fruit and green leaves

Native Image Retrieval

Can match details omitted from the caption: the geometry of the bird’s white eyebrow stripe, its yellow-green plumage, the mixture of smooth and weathered fruit, the leaves’ deeply ribbed texture, and the image’s warm palette and shallow-focus composition.

The caption is a compressed interpretation of the image. Capturing every potentially useful detail requires long or specialized captions, written with the eventual search query in mind. Native image embeddings preserve visual characteristics without requiring the caption to anticipate which details matter.

This enables searches that are difficult to express precisely with words. You can describe an image you want to find, provide another image to locate visually similar results, or combine both, such as “a bird with similar markings” or “a bird perched on a leafy branch with plums.” It is useful for product discovery, screenshot matching, charts, diagrams, scanned documents, and other collections where color, texture, composition, or spatial relationships matter.

Here’s how a query moves through AI Search. First, the query is optionally rewritten, then embedded (image queries are embedded directly by multimodal models, or captioned first by text-only models). Vector and keyword search run in parallel, and results are fused and optionally reranked. The top chunks are returned, or passed to a generation model to write an answer.

Bigger files and OCR for scanned documents

AI Search now accepts your text files (Markdown, HTML, CSV, JSON and similar) and PDFs up to 10 MiB, up from 4 MiB. Many PDFs are really scanned images with no extractable text. For those, turn on OCR and AI Search reads the text from each page before chunking and embedding it. OCR is available to every account and is billed under the new AI Search pricing as image processing ingestion tokens.

Now in GA: billing and pricing for AI Search

During our August 2026 Agents Week, we announced preview pricing for AI Search. With the product going GA today, we’re announcing billing for AI Search that is going live on November 1, 2026. We’ll send a reminder email before billing is enabled.

AI Search pricing is designed, so you can estimate your bill before you index a single file. You pay for three things: the content you ingest, the data you store, and the queries you run. The work in between (parsing, chunking, embedding with Workers AI models, keyword indexing, and reranking) is included. There are no instance hours, capacity units, or monthly minimums to size up front, and small projects fit inside the free monthly allotment.

Ingestion pricing is based on one rate per token with whichever Workers AI embedding model you pick, and tokens are counted the same way for every model. Switching from a text-only embedding model to a multimodal one doesn't change what you pay to ingest, unless you are also processing images (add-on fee). Storage is priced on the size of data in your indices. Querying is priced based on the type of query (semantic vs. full-text) and how many queries you send.

Estimating your cost comes down to how much content you index, how much you store, and how many queries you expect. Here's the pricing we announced in preview, with one tweak that we’re making: on the free monthly allotment, you will receive 1,000 semantic queries and 1,000 full-text queries (instead of a shared pool of 2,000 queries).

Pricing

Free monthly allotment (all Workers plans)

Ingestion

Base Ingestion

$0.75 / 1M tokens

5M tokens †

Image processing (add-on)

+$0.50 / 1M tokens

5M tokens †

Storage

Stored data

$2.00 / GB-month

10 GB

Query

Semantic (hybrid and vector search)

$0.75 / 1k queries

1,000 queries

Full-text

$0.10 / 1k queries

1,000 queries

Embedding and Reranking

Ingestion and query

Free with select Workers AI models; third-party billed separately

N/A

† A single pool of 5M ingestion tokens per month, covering any file type currently supported (e.g., text, images).

What’s next

Multimodal embedding support is just the first step; we’re building an ingestion pipeline to support full video and audio processing to allow our customers to search their rich media assets.

We’re also refactoring the keyword search engine so that it scales better with your content requirements, particularly for when you have big data stores where the current implementation has limits.

Finally, we’re developing better and simpler ways to enable AI Search and create indexes for websites already running on Cloudflare. This ensures AI agents can discover, explore, and consume content more easily and efficiently.

Stay tuned for these follow-up announcements and more.

AI Search is now generally available to enable and use today. Get started with our new multimodal embeddings, bigger files, OCR features, and our new managed instance pricing. Check out the AI Search developer docs for more information.

Support for modern cryptographic algorithms in Workers

Post Syndicated from Thibault Meunier original https://blog.cloudflare.com/workers-ml-kem-ml-dsa-support/

Today, Cloudflare Workers is adding support for post-quantum-resistant algorithms within Web Crypto. These are defined in Modern Algorithms in the Web Cryptography API draft community group report, and include:

  • ML-KEM-768 and ML-KEM-1024 for key encapsulation
  • ML-DSA-44, ML-DSA-65, and ML-DSA-87 for signatures
  • encapsulateBits(), decapsulateBits(), encapsulateKey(), and decapsulateKey()
  • getPublicKey()
  • SubtleCrypto.supports()
  • JWK import and export for these algorithms

For developers preparing for the post-quantum transition, these opt-in Web Crypto APIs make it easier to experiment with ML-KEM and ML-DSA without bundling a separate cryptographic implementation. They do not provide a full migration path, but rather building blocks that can be used to validate your integration.

This support is available behind the webcrypto_modern_algorithms compatibility flag while the specification is still moving.

Background

Web Crypto is one of those APIs you only notice when it lacks the primitive you need. If you want to experiment with newer post-quantum algorithms in a JavaScript environment, it’s hard. You either cannot build the protocol directly on top of Web Crypto, or you bring your own cryptography implementation in JavaScript or WebAssembly.

Neither option is ideal. They put the burden of selecting and maintaining cryptographic implementations on implementers, who see their applications get larger as they bundle cryptographic code. And this is work that needs to be reproduced for all downstream libraries. As the ecosystem needs to transition to post-quantum-resistant algorithms sooner than expected, we cannot wait for better post-quantum algorithms. Developers need access to these primitives now so they can test, evaluate, and improve post-quantum integrations.

In this post, we’ll explain how you can implement these primitives today, and start to prepare your applications for the post-quantum era.

The short version

Here is what ML-KEM looks like in Workers. One side has a public key. The other side encapsulates a shared secret to that public key. The holder of the private key decapsulates it and gets the same secret.

There is no encryption in that snippet yet. ML-KEM gives both sides shared key material. Protocols such as Hybrid Public Key Encryption (HPKE) then feed that material into a key schedule and an AEAD such as the AES-GCM algorithm.

ML-DSA is closer to what most developers have already seen with Ed25519 or ECDSA: generate a key pair, sign bytes, verify bytes.

These examples are deliberately small. They are not protocols. They are the JavaScript hooks for cryptographic primitives that protocols need.

Why this matters

Post-quantum migration is not one switch. It is a lot of protocols, libraries, services, and deployment environments learning how to use different primitives.

Some of that work is already visible in TLS and SSH. OpenSSH added support for mlkem768x25519 in 2024. HPKE has a draft for post-quantum and hybrid KEMs ongoing at the IETF. The IETF published RFC 9964 for ML-DSA in JOSE, as well as an adopted draft for JWE using PQ & PQ/T HPKE. HTTP Message Signatures can use different signature algorithms, as long as the signer and verifier agree on how to produce and verify the signature.

To support all these on Cloudflare Workers, developers needed support for the underlying cryptographic primitives within Web Crypto.

Without it, a Workers developer could still experiment with post-quantum code, but they had to bundle a separate implementation. That is useful for portability and for early experiments, but it is not where we want every production application to end up.

Signing JWTs with ML-DSA

Signed JSON Web Tokens (JWTs) are a familiar example that protect using JSON Web Signatures (JWS). With a panva/jose library that maps ML-DSA-* algorithms to Web Crypto, the application code is as follows:

JWTs are only one example. The larger point is that libraries can delegate ML-DSA operations to the runtime instead of carrying their own implementation for every environment. With Workers supporting ML-DSA natively, libraries can delegate signing to the runtime rather than shipping their own implementation.

HPKE and OHTTP

ML-KEM is a key encapsulation mechanism. On its own, it gives two parties shared key material. HPKE turns that into a complete encryption construction by adding a key schedule and an AEAD.

Libraries such as panva/hpke are already structured around Web Crypto and runtime support. With the Workers runtime exposing ML-KEM, HPKE implementations can use the native primitive where available.

This is the shape we want for protocols such as OHTTP as well (which we’ve discussed before). OHTTP uses HPKE. If HPKE can use a post-quantum KEM through Web Crypto, then that peer can start discussing migrating to a ciphersuite that supports these primitives.

Libraries may require runtime-specific integration changes. Here, HPKE.CipherSuite selects implementations according to the algorithms available in the runtime.

Getting a public key from a private key

Several protocols need to publish or derive a public key after loading a private key. Previously, this often meant keeping both around or doing format-specific work.

The new getPublicKey() helper does the direct thing:

For ML-KEM, the usage is different because public keys encapsulate and private keys decapsulate:

This is a small API that aims to remove code used a lot across libraries that deal with public key cryptography.

Checking support

Because the API is not yet supported across runtimes, libraries should check for it instead of assuming it exists everywhere.

Libraries that run across Workers, Node.js, Deno, browsers, and other Web-interoperable runtimes need this kind of check. It also helps when only part of the modern algorithms proposal is implemented.

What is supported today

The initial Workers implementation supports ML-KEM-768 as a KEM and ML-DSA-44 as a signature algorithm. All require the webcrypto_modern_algorithms flag to be set.

For completeness, we also support ML-KEM-1024, ML-DSA-65, and ML-DSA-87. ML-KEM-512 is not supported because the BoringSSL version used by Workers does not expose it. Rather than add a separate implementation just for that variant, we are starting with the algorithms available through the native crypto library.

The most recent list of supported algorithms can always be found on our developer documentation.

How it’s been implemented

Workers run on workerd. It’s an open-source runtime built on V8. The implementation adds ML-KEM and ML-DSA support to workerd's Web Crypto layer, backed by BoringSSL primitives.

This change also adds Web Platform Tests for the modern algorithms API surface, Workers-specific tests for compatibility flag behavior, and TypeScript definitions under the new Workers types.

We split this out from a larger proposal from panva. The change discussed in this blog, which is the first part of the modern Web Crypto algorithm specification, focuses on ML-KEM, ML-DSA, helper APIs, and JWK support. Other algorithms from the W3C Web Incubator Community Group (WICG) proposal, such as SHA-3, cSHAKE, TurboSHAKE, and ChaCha20-Poly1305, are not part of this initial change.

That smaller scope makes review easier. It also gives library authors something concrete to test before the whole modern algorithms proposal is implemented.

Note that ML-DSA public keys and signatures are substantially larger than RSA or Ed25519. The integration of these algorithms in the runtime improves performance and reduces the need for bundling. However, it does not change the reality that the size of keys, signatures, or ciphertext is increasing, on the wire or when stored.

What may come next

The WICG proposal covers more than ML-KEM and ML-DSA. We have not implemented the following from the original contribution by Filip Skokan in cloudflare/workerd#6403, which will need further review. This includes the SHA-3 hash function, ChaCha20-Poly1305 AEAD (discussion about XChaCha20-Poly1305 in wicg/webcrypto-modern-algos#1), cSHAKE, TurboSHAKE, and HPKE (discussed in wicg/webcrypto-modern-algos#2). An implementation has already been tested against panva/hpke and panva/jose test suites to verify the implementation.

There is also a practical question about when this should become default, rather than opt-in. For now, all these algorithms are gated behind a compatibility flag. The API is based on a draft, and we want feedback from library authors before treating it as stable.

Start experimenting today

This change does not make every protocol post-quantum by itself. It gives Workers developers and library authors the primitives they were missing: ML-KEM for key encapsulation, ML-DSA for signatures, and helper APIs that make those primitives usable through Web Crypto.

If you maintain a library that currently bundles its own post-quantum implementation, this is a good time to try the native API and tell us what does not fit. The fastest way to find the rough edges is to put real protocol code on top of it. All the details are in our changelog.

We would like to thank Filip Skokan for the original contribution and iterations, Felix Hanau, James Snell, Bas Westerbaan, and Peter Wu for reviewing the code, and Daniel Huigens for co-authoring the specification work this implementation follows.

Introducing Workers KV Instant — powered by Quicksilver

Post Syndicated from Rob Sutter original https://blog.cloudflare.com/workers-kv-instant/

Today, we’re introducing Workers KV Instant, a new mode for Workers KV that pushes your changes globally for instant availability without cold read penalties.

Workers KV has been one of our most popular services on the Developer Platform since launching during Birthday Week in 2018. It’s great for quickly accessing data like static assets and user configuration that is written occasionally but read frequently. We use it ourselves across many Cloudflare products.

We also have another key-value store, Quicksilver, which we’ve blogged about many times since introducing it in 2020. We designed Quicksilver for incredibly fast global replication and low-latency access, and nearly every request to Cloudflare looks up at least one key in Quicksilver. People have asked us for years, but we’ve never made Quicksilver available to our customers.

We’re changing that today with Workers KV Instant. KV Instant mode provides the same API as Workers KV, but powers it using Quicksilver. KV Instant offers 100 times faster p99 reads and immediate updates, with no need to wait for a TTL to expire. It’s not for every type of data, but, for infrequently updated application configuration data — the same thing we use Quicksilver for ourselves — KV Instant shines. 

100x faster reads than Workers KV

KV Instant offers read latency that is over 100 times faster than classic mode, with reads resolving in under two milliseconds even at the 99th percentile of response time (p99), and 95th percentile (p95) times measured in microseconds. Writes are pushed to the edge over 20 times faster, with 99% of all writes replicating in around 250ms.

These high-performance characteristics of KV Instant make it ideal for reading data in the hot path of your applications, especially flags and settings that should be available globally nearly instantly after they’ve been written.

Mode

p99 reads (cached)

p99 reads (all)

median write replication

p95 write replication

p99 write replication 

Instant

N/A

1.62 ms

107 ms (1)

181ms (1)

256 ms (1)

Classic

160 ms

287 ms

< 1 s (2, 3)

< 1 s (2, 3)

4.38 s (2)

Table notes:

  1. Time to replicate to all edge locations (over 300 as of publication)
  2. Time to replicate across all required storage backends
  3. We do not have sub-second fidelity for replication lag in classic mode

KV Instant is powered by Quicksilver v2, a key-value store developed internally by Cloudflare to enable fast global replication and low-latency access on a planet scale.

The same simple API as Workers KV — get(), put() list(), delete()

KV Instant uses the familiar Workers KV API you build with today.

For example, let’s say you’re working on a big product launch, and need to be able to switch what’s on the homepage right at 10:13 AM when the product is introduced at the keynote on stage. You need some key that you can read, that introduces near zero latency, you can read on every request no matter the scale, and updates instantly when you change it.

Most binding operations are compatible with the Workers KV classic equivalents. There are three key differences when working with KV Instant:

  • You must specify KV Instant mode when creating a KV namespace. (pass the ”mode”: “instant” attribute)
  • Metadata is not supported, so getWithMetadata calls always return null and there is no support for passing metadata in put.
  • list operations in KV Instant return all matching keys in a namespace; there is no pagination.

For additional API examples, see the Workers KV docs.

Pricing — reads cost 60% less than classic Workers KV

KV Instant is priced to fit the read-heavy, small data workloads it excels at serving. Because we propagate data to every Cloudflare location, using the same Quicksilver key-value store we’ve spent years learning how to operate at scale on the hot path of every request, we can offer pricing for reads that is 60% less than Workers KV, and much less than other global configuration products.

Conversely, storage and Class A operations are significantly more expensive than Workers KV. If you need to store large amounts of data, or update it frequently, Workers KV continues to be a great fit. Each mode is designed for a very different type of data and access pattern.

KV Instant namespaces are priced in three dimensions: data storage, class A operations, and class B operations.

Class B operations (reads)

Class A operations (put, delete, list)

Storage

Workers KV Instant

$0.20 per million

$0.10 per operation

$100 per MB, per month

Workers KV

$0.50 per million

$5.00 per million

$0.50 per GB, per month

Storage

Storage is billed at $100 per MB, per month. Each key can be up to 300 bytes, and values can be any size that does not cause the namespace to exceed one megabyte in total size. KV Instant namespaces can contain up to 10,000 key value pairs of any type.

Class A operations

Class A operations  (put, delete, and list) are charged at $0.10 per operation. Each key written or deleted counts as one Class A operation. Each list request counts as one Class A operation, regardless of how many keys are returned in the response. A single list operation can return all the key value pairs in a namespace in a single page.

Because writes must pass through a single system of record, KV Instant also restricts write frequency to one write per namespace per second. This is similar to classic Workers KV’s restriction of one write per key per second, and makes it easier for you to reason about update order in your application.

Class B operations

Class B operations (get) are charged at $0.20 per million keys requested, 60% cheaper than Workers KV default mode. When requesting multiple keys in a single get operation, each requested key is billed as one class B operation. For example, the following approaches both incur three class B operations and are equivalent from a billing perspective.

Workers KV Instant is in private beta

KV Instant is launching today in private beta. We’re excited to start working with customers who want to try it, then open it up more widely, and would love to hear from you. You can sign up for the private beta here. Tell us what you’re building!

How AI Is Changing the Roles Required in the Security Operations Center

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/ai-changing-security-operations-center-roles-soc

As AI takes on more of the enrichment, correlation, and initial assessment inside the SOC, roles, skills, and KPIs still require deliberate redesign. Security leaders need to decide where automation is dependable, where human judgment should remain decisive, and how teams should be measured when alert handling is no longer the center of the operating model

The Gartner® report, The Roles Required for the AI-Enabled Security Operations Center (SOC), examines the roles and capabilities Gartner expects the SOC to require as AI becomes embedded in security operations. Rapid7 is offering complimentary access to the research, which we believe can help leaders plan their future workforce, operating model, and investment priorities.

How will AI change the role of SOC analysts?

Many analyst roles and performance measures remain closely tied to handling individual alerts. As organizations introduce AI SOC agents to support enrichment, correlation, and initial assessment, leaders may need to reconsider where human expertise creates the greatest operational value.

Gartner states, “Human analysts must transition from alert triage roles to end-to-end case ownership and effective response option communication.” At Rapid7, we believe this shift creates an opportunity for analysts to focus their judgment on validating context, coordinating response, and communicating decisions clearly.

Gartner also recommends, “Stop recording alert metrics and run the SOC on cases and decisions.” Robert Willis, VP of Managed Detection and Response at Rapid7, puts it plainly: “Alert volume is a distraction. The real measure of SOC value is decision quality, did you get the right answer, fast enough to act on it? MDR is built to deliver exactly that: answers, not alerts, so your team can focus on ownership and response rather than triage.” MDR can help manage alert volume while adding investigation and response capacity, giving internal teams more space to focus on the cases that require their context and ownership.

Where does human judgment remain essential?

Rapid7’s experience applying agentic AI within our MDR SOC shows how this division of work can operate in practice. Our agentic workflows have saved more than 200 analyst hours each week and achieved 99.93% benign-disposition accuracy, reducing the repetitive work involved in initial triage and giving analysts more time for complex, ambiguous, and higher-stakes investigations.

We believe human judgment remains essential when a decision carries operational consequences. AI can gather evidence, correlate activity, and present a structured rationale, while analysts validate the conclusion, consider the organization’s priorities, and determine the appropriate response. This human-led, AI-driven model combines machine-speed investigation with accountable decision-making.

Why are SOC engineering roles expected to expand?

As AI-enabled workflows expand, engineering discipline is likely to become increasingly important within security operations. Reliable processes require people who understand threats and security data, can test automated workflows, and can establish appropriate controls around AI-supported decisions.

The report includes the strategic planning assumption, “By 2028 there will be 50% more engineers in security operations teams than analysts.” Gartner also advises organizations, “Redefine detection engineering role descriptions and hiring requirements. Expand them beyond rule writing to include prompt design, workflow testing, and AI output validation.”

From Rapid7’s perspective, detection engineering is developing into a broader operational discipline. Data quality, testing, version control, rollback procedures, documentation, and human approval paths all contribute to dependable AI-enabled workflows. Investing in these capabilities can help teams use automation confidently while keeping people central to consequential security decisions.

Why should Exposure Management be a continuous SOC function?

The report also considers how security operations can identify and validate weaknesses before they contribute to an incident. Gartner states, “Exposure management is the emerging SOC capability to invest in before anything else.”

At Rapid7, we believe exposure management should become a standing operational discipline that connects discovery, validation, prioritization, and remediation with detection and response. Exposure Command can help teams understand which exposures present the greatest risk and direct remediation accordingly, while MDR provides additional expertise and capacity to investigate and respond when threats emerge.

Together, these capabilities support a human-led, AI-driven operating model focused on informed decisions, continuous exposure reduction, and effective response. Access the complimentary Gartner report, The Roles Required for the AI-Enabled Security Operations Center (SOC), to explore how Gartner expects SOC roles and responsibilities to evolve.

Download the full Gartner® report →

Introducing Cloudflare Basin: an open, serverless data platform, now generally available

Post Syndicated from Marc Selwan original https://blog.cloudflare.com/cloudflare-basin/

During Birthday Week 2025, we announced the Cloudflare Data Platform, a suite of products that ingest, store, and query your analytical data. Today, we’re announcing that the platform is generally available, and we’re giving it a new name: Cloudflare Basin.

Basin is a serverless data analytics platform built on Apache Iceberg, the open standard for data lakes, and R2 Object Storage. The Basin family includes:

  • Basin Pipelines, formerly Cloudflare Pipelines, receives events from Workers, HTTP, or Cloudflare Logpush, transforms them with SQL, and writes them as Apache Iceberg tables or files in R2.
  • Basin Catalog, formerly R2 Data Catalog, manages Iceberg metadata and automatically maintains tables to keep them fast and cost-efficient.
  • Basin SQL, formerly R2 SQL, is our serverless, distributed SQL engine for querying Apache Iceberg tables directly on Cloudflare.

Basin brings an end-to-end analytics platform to the Developer Platform, enabling you to collect data from a variety of sources, such as apps, infrastructure, devices, and other Cloudflare services, then query it to answer analytical questions.

We set out to build a data platform last year when we saw two fundamental developments that changed how modern data applications were being built. First, Apache Iceberg emerged as the standard open table format, making data portable across nearly every major query engine. Second, we started seeing developers bring their analytics data to R2 where the lack of egress charges made it practical and cost-efficient to actually access their data from different tools, teams, regions, and cloud providers.

So, when we launched Basin in open beta, developers — including our billing and infrastructure teams at Cloudflare — immediately started adopting these services for a variety of use cases including using real-time data to optimize e-commerce sites, long-term storage and reporting of billing metrics, and ingesting and querying telemetry from Cloudflare’s infrastructure to measure and improve utilization and efficiency.

“We moved our entire company's data pipeline to Basin Pipelines, Catalog, and SQL, replacing a complex AWS S3 and Athena setup with a cleaner, serverless architecture that reliably handles all of our event data. -Dax Raad, Co-Founder, Anomaly

Our early adopters taught us a great deal about what it means to run an analytics platform on the edge. We spent the past year improving Basin around three specific areas that hone in on what makes analytics in Developer Platform unique: speed, openness, and cost efficiency.

Basin is built for speed — whether it’s about getting started or executing large queries. You can create a Basin Catalog, set up a Pipeline to ingest data, and query it with Basin SQL in seconds. This matters as we see more data applications being built from prompts to coding agents, which would otherwise have to wait and poll for resources or data. As datasets grow, Basin Catalog compacts metadata and data files to reduce I/O and generates statistics for query planning. Basin SQL uses those statistics to split queries into smaller tasks and distribute them across Workers, keeping queries fast and consistent as datasets scale.

A large driving force in the development and adoption of Basin is the continued growth we are seeing in the open Apache Iceberg ecosystem. Developers have been rallying around the radical idea that you should own and be in control of your own data — separating the storage layer from the compute layer and allowing you to use the right query engine for the job. With Basin, you can read and write your data using any Iceberg-compatible engine, including PyIceberg, DuckDB, Snowflake, and Apache Spark. That kind of data portability is only possible with free egress, which allows developers to access their data in Cloudflare from the wide variety of tools in the ecosystem, regardless of region or cloud.

“Bobsled is a data product platform that the world's most advanced data teams use to build and distribute AI-ready data to partners, vendors and customers," said Julien Grobbelaar, Head of Platform at Bobsled. "Basin allows us to build data products that can be made accessible in any region of every major data and AI platform, all at production-grade reliability and a fraction of the cost thanks to zero egress fees.” 

In addition to free egress, our serverless architecture allows us to offer further cost efficiencies to our customers with usage-based pricing. You are only billed when Basin ingests, processes, or queries your data. Developers can build out analytics for hobby projects at little to no cost, while our pricing scales economically for larger enterprise use cases. There are no hourly charges or separate infrastructure costs to worry about.

If you are ready to get started, refer to the Basin tutorial for a step-by-step guide on how to use Basin Pipelines to deliver events to an Apache Iceberg table managed by Basin Catalog, and query them with Basin SQL. Read on to learn more about Basin and where we are going next.

Why Basin?

We launched these products last year as the Cloudflare Data Platform, which has served us well for the first year of availability. For our GA launch, we decided we needed a new name that encompasses our ambitions for the platform, links together all the products, and is a bit punchier.

A basin is where rivers from many sources come together to a single point. We felt that Basin perfectly captures how the platform is used: Pipelines brings data into Basin Catalog while Basin SQL makes it instantly queryable. A fun fact: roughly 20% of Earth’s land drains into endorheic basins, much like over 20% of the web sits behind Cloudflare’s network. 

Today, Basin is made up of three products: Pipelines, Catalog, and SQL, covering ingestion, storage, and querying, and will expand over time with more products managing the rest of the analytical data lifecycle.

Basin Pipelines

Before you can query your data, your events need to be ingested, structured to a schema, and written to object storage. This is the role of Basin Pipelines. It accepts events through HTTP endpoints or Workers bindings, processes them according to a SQL query, and delivers them to Basin Catalog as Apache Iceberg tables or R2 as JSON or Parquet files.

Since our beta launch, users have created tens of thousands of Pipelines for a wide variety of use cases. For example, a common pattern we see is using Pipelines to transform Cloudflare HTTP logs before storing them:

Doing this work during ingestion can significantly reduce the storage footprint, reduce noise from dynamic data sources, and can help prevent sensitive or unnecessary values from being written.

Since the beta, we have greatly expanded the scalability of Pipelines: we now support ingesting up to 3GB/s per stream. We’ve also expanded the feature set and integration with other Cloudflare systems:

  • Cloudflare Logpush integration: you can transform Cloudflare logs with SQL and store them as compressed Parquet files or Iceberg tables, ready to query with Basin SQL or another engine.
  • Worker bindings are schema-aware. Running wrangler types generates TypeScript types from a stream's schema, catching missing fields and type mismatches before deployment.
  • Data quality errors are visible. The dashboard and GraphQL API surface dropped events and distinguish missing fields, type mismatches, parse failures, and null values.
  • The entire ingestion path can be infrastructure as code. Terraform resources cover the catalog, stream, sink, and the SQL that connects them.

Next we plan to expand Pipelines capabilities even further, including:

  • Custom partitioning when writing to Basin Catalog
  • Schema migrations, and updatable configuration and Pipelines SQL
  • Support for Iceberg V3, including the Variant type for efficient querying of semi-structured data
  • Stateful processing to support workloads such as streaming aggregations, joins, and incrementally updated materialized views

Basin Catalog

Basin Catalog was the first product we launched in the family last year. Since then, we’ve seen thousands of developers use Basin Catalog for simple use cases such as giving DuckDB a structured way to access analytics data in R2, all the way to developers building complete enterprise data sharing platforms, fully taking advantage of zero egress fees and easy-to-use APIs.

Basin Catalog is the easiest way to get started with Apache Iceberg. Just run:

You instantly get a fully managed Apache Iceberg REST catalog that automatically performs routine maintenance required to keep those tables performant and healthy.

When we announced the Data Platform, Basin Catalog had just added automatic compaction. Since then, it has evolved to maintain healthy tables as your data scales:

  • Per-table compaction policies let you choose target file sizes based on each table's access pattern.
  • Automatic snapshot expiration removes old Iceberg snapshots according to a retention policy, while preserving a minimum number of recent snapshots.
  • Unreferenced data-file cleanup reclaims storage when snapshots expire, without requiring a separate Spark maintenance job.
  • Manifest optimization consolidates and clusters fragmented manifests by partition before compaction, reducing metadata I/O during query planning.

We have some exciting features in the works for Basin Catalog including:

  • A new way for compaction to efficiently sort and cluster data for improved query performance
  • More granular auth controls for namespaces and tables
  • Jurisdiction support to adhere to data sovereignty and compliance requirements

Basin SQL

Basin SQL is our serverless, distributed query engine for Apache Iceberg tables stored in Basin Catalog. It’s designed for reading large datasets and automatically scales across Cloudflare's global network. There are no clusters or resources to provision, just a readily available API for you and your agents to immediately start querying your data.

At beta launch, Basin SQL was great at filtering and exploring large event and time-series tables. Over the last year, Basin SQL has evolved to support hundreds of functions including:

  • Standard and approximate aggregations, GROUP BY, HAVING, and schema-discovery commands
  • More than 190 scalar and aggregate functions across strings, timestamps, regular expressions, cryptography, statistics, arrays, maps, and structs
  • CASE expressions, common table expressions, casting, arithmetic, and EXPLAIN
  • Inner, outer, semi, and anti joins; subqueries; self-joins; and multi-table queries
  • DISTINCT, UNION, INTERSECT, and EXCEPT
  • Window functions, QUALIFY, grouping sets, rollups, and cubes
  • A suite of JSON functions

Suppose your Pipeline delivers application events into one table and account data into another. You can now join those tables, aggregate activity by customer, rank the results with a window function, and filter the ranking in one query:

You can run Basin SQL from Wrangler or the API, or open the built-in editor in the Cloudflare dashboard. The editor provides syntax highlighting and autocomplete, a browser for namespaces and tables, query statistics and plans, and exportable results. It makes the path from a new table to a useful answer a matter of seconds.

The team isn’t stopping here and is currently working on:

  • Advanced statistics and adaptive scheduling to improve performance and efficiency of queries
  • Full data definition language (DDL) support directly from Basin SQL
  • Iceberg V3 support including support for the VARIANT and geospatial types

What comes next

Our future vision is that data infrastructure is completely abstracted away. Storage formats, products, and resources are just implementation details — important ones that help enable the important outcomes — but tend to get in the way. We’re building towards a platform where developers start with questions rather than CREATE statements or CLI commands. We’ve laid the foundation for that vision, and now we’re building towards that vision including:

  • Support for the latest Apache Iceberg spec across the entire platform, unlocking more flexible ways to use your data
  • Push-button ingestion sources and destinations, with zero-configuration connections across Cloudflare's developer and observability products
  • Advanced adaptive table-maintenance strategies in Basin Catalog that automatically organize data around real query patterns
  • Continued expansion of SQL compatibility, performance, and observability for increasingly complex analytical workloads
  • More ways to continuously process data in real-time and trigger actions based on the signals within the data
  • Tools for adhering to data compliance and sovereignty rules across the platform

We will continue to build with open standards: using open formats and protocols, contributing improvements to the projects we depend on, and making sure your data remains available to the broader ecosystem.

Get started

Basin Pipelines, Basin Catalog, and Basin SQL are generally available today. You can use them together as an end-to-end platform or adopt the parts that fit your existing architecture.

Follow the getting started tutorial to ingest events, create an Apache Iceberg table in Basin Catalog, and query it with Basin SQL. Visit the Basin documentation for product guides, pricing, limits, and integrations.

Existing Cloudflare Pipelines, R2 Data Catalog, and R2 SQL configurations will continue to work.

We are excited to see what you build. Share your feedback with us in the Cloudflare Developer Discord.

Connected Cars Are a Surveillance Platform

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/10/connected-cars-are-a-surveillance-platform.html

Researchers at Northeastern University, in collaboration with Consumer Reports, evaluated how much modern cars spy in their drivers:

To determine this, CR dug through thousands of pages of automakers’ privacy policies and asked questions of 15 different automakers­BMW, Ford, General Motors, Honda, Hyundai, Kia, Mazda, Mercedes-Benz, Mitsubishi, Nissan, Stellantis, Subaru, Tesla, Toyota, and Volkswagen. We also reviewed corporate, regulatory, and legal filings from data brokers operating in the “insurtech” industry­the technology companies and data brokers that help insurance companies set their rates. And we spoke to several car privacy experts, who, at industry conferences and in market reports, have described the profit potential of individual driving data as the “new oil.”

We found that while some automakers may obtain your “permission” to collect your driving data, you may agree without knowing you’ve done so. For example, after buying a new car, when you first turn on the infotainment system­the onboard display that can allow you to control heat and AC, GPS navigation, music, and more­you are usually shown a series of consent forms, including ones about privacy policies. Those forms can also pop up on a connected mobile app. Many of us simply accept their terms without reading through them.

Basically, your car’s manufacturer has you under constant surveillance, and they use that data against you.

The companies on the receiving end of your data, our investigation has found, include car insurers and lenders that are partners in “telematics data exchanges,” which compile driving data on millions of drivers, thousands of data brokers that create personalized risk scores, companies selling infotainment and WiFi hotspot products, and even local and state government agencies working on planning, traffic, and safety initiatives.

Remember the adage “If you’re not the customer, then you’re the product”? (The sentiment is older than you think.) Turns out that with modern internet-connected everything, you’re the product even if you are the customer.

Училище за радикализация под носа на държавата

Post Syndicated from Светла Енчева original https://www.toest.bg/uchilishte-za-radikalizatsiya-pod-nosa-na-durzhavata/

Училище за радикализация под носа на държавата

Децата да прекарват по-малко време в социалните мрежи и да четат повече книги. Свикнали сме да чуваме съвети в този дух, особено на фона на ежегодните статистики колко малко книги се четат в България. Ала по-важно от количеството прочетени книги е какви са самите те. Има много, които няма да допринесат за развитието на личността на читателите си. А някои книги е по-добре изобщо да не са били написани.

На бюрото ми е отворена книгата на Ален Симеонов „Училище за ловци на педофили“.

Поръчах си я от онлайн книжарница веднага след като научих за петицията за изтеглянето ѝ от пазара. Макар в петицията да са се подписали по-малко от 600 души, книгата бързо престана да се предлага и към днешна дата може да се поръча (срещу 16 евро) само от личния сайт на автора ѝ (не слагам линк към него от етични съображения, но той лесно може да се намери).

Тази скоростна реакция, предполагам, се дължи по-скоро на чувството за самосъхранение у търговците, отколкото на вслушване в аргументите в петицията. След убийството на Георги Кузев от непълнолетни „ловци на педофили“ предлагането на книгата нямаше как да направи добро впечатление.

Издавам тази книга и заради юридическата ми защита и покриването на отсъдените ми глоби,

пише Ален Симеонов в увода. След смъртта на Кузев обаче онова, което е трябвало да послужи като юридическа защита, заприличва на самопризнания, макар и за непряка вина. Разбира се, ако има кой да ги потърси. Група непълнолетни, гаврили се с човек до смърт и снимали се с него, правейки специфичния знак с прегънат палец, който Симеонов е възприел от покойния руски „ловец на педофили“ Максим Марцинкевич, известен с прозвището Тесак. И този знак е не само на корицата на книгата и не само подробно е разяснен в нея, а и заема цялата страница 5.

Отговорност от Ален Симеонов на този етап обаче не изглежда да се търси.

Той самият побърза да се разграничи от тийнейджърите, убили Кузев. Не защото според него животът на мъртвия има ценност, а защото е „безполезно“ да се убива – „педофилите ще се превърнат в жертва“, а извършителите ще влязат в затвора.

Кой още има принос, за да се стигне до убийството на Георги Кузев?

Светла Енчева проследява нишката от хора, събития и обстоятелства, довели до убийството на Георги Кузев – от нормализирането на омразата и самоуправството до ролята на медиите, институциите и политиците. „Обичайните заподозрени“ – родителите и социалните мрежи, са само част от картината.

Общественото внимание бързо беше изместено първо към пловдивския клон на неонацистката организация „Кръв и чест“ (срещу чийто лидер вече са повдигнати две обвинения – за подбуждане към омраза и дискриминация и за ръководене на група, целяща престъпления на такава основа). И към други скандали, били те нови или претоплени. Ето защо е важно за „Училище за лов на педофили“ да се говори, преди темата съвсем да е потънала.

Какво представлява книгата

Зад „Училище за ловци на педофили“ не стои издателство, но книжното тяло е луксозно. То е с твърди корици, качествена хартия и множество цветни снимки. Съдържа 288 страници с размер 156 на 230 мм. Липсва информация за тиража, така че е трудно да се прецени колко е струвало издаването на книгата. Но тъй като за нея очевидно не са пестени средства, изглежда странно твърдението на автора, че парите от продажбите ѝ ще отиват за покриване на глоба от 5000 лв., която е осъден да плати. Защото който може да си позволи подобно издание, вероятно може да отдели и 2556,45 евро за глоба. По-скоро с този аргумент се сугестират последователите на автора да си купят книгата на своя вдъхновител, смятайки, че така му помагат.

Кой има принос за книгата

На отделна страница авторът изразява признателност „към проф. д-р Йоаким Каламарис, с чието съдействие тази книга се издава“.

Йоаким Каламарис не е професор, макар да се представя за такъв и медиите да го титулуват по този начин. През 2017 г. е избран за доцент във Висшето училище по сигурност и икономика в Пловдив (което от 2025 г. се нарича Академия по национална и информационна сигурност). Той е дошъл от Гърция в България още като студент, останал е в страната и притежава бизнес с недвижими имоти. От 2014 г., макар да е гръцки гражданин, е почетен консул на Уругвай в България. Притежава и фондация.

За Каламарис се знае, че е осъдил прокуратурата заради рекет, на който е бил подложен от покойния Мартин Божанов – Нотариуса. Понякога се изказва по теми, свързани с международното положение (например тук и тук), позициите му по които може да се обобщят така: Путин и Тръмп са големите и силните, а Европа, либералите и Байдън – не.

Редактор на книгата е Еленко Ангелов. Той определя себе си като „психолог, терапевт, писател и отстранител на проблеми“. Спектърът на занятията, с които си вади хляба, е широк – от бодибилдинг и бокс, през психотерапия, та до ораторско майсторство. Всичко това омесено със солидна доза окултизъм и неканонични възгледи за Библията (например че има тайни евангелия за Христос).

Юридически консултант на „Училище за ловци на педофили“ е Станислав Трендафилов, който е и адвокат на Симеонов (про боно, както се споменава в книгата). Той е бил адвокат и на ЦСКА – София, но и след като е престанал да е такъв, проявява ангажираност по теми, свързани клуба.

Макар корицата да прилича на правена с изкуствен интелект, книгата си има и дизайнер – Мила Иванова.

Какво (не) знаем за сексуалните злоупотреби с деца

Какво знаят институциите за сексуалните злоупотреби с деца в България и какви мерки предприемат? Теодора Станимирова се сдоби с информация от ВСС, МВР, АСП, ДАЗД и МЗ, разговаря с експерти и ни разказва какво е научила.

Структура

288 страници звучат впечатляващо, но трябва да се има предвид, че значителна част от тях заемат транскрипти и преразкази на чатове и видеозаписи – както на множество случаи на „лов на педофили“, записи от които са качени и на сайта на автора, така и на интервюта с участието на Симеонов. Доста място заемат и снимките, както и фотокопия от медийни публикации и документи (заповеди за задържане, съдебни решения и пр.). Между тях са коментарите и интерпретациите на автора, разказите му за различни събития, примерно за делата срещу него, и възгледите му по различни теми, юридически анализи и психологически размишления.

Повествованието е като цяло хронологично, с изключение на уводните глави за Джефри Епстийн и Тесак, както и заключението, но на места има разхвърлян вид. Това се дължи както на размислите и теорията, накъсващи разказа, така и на това, че някои теми се засягат по няколко пъти (например за наркотиците), а други остават недоизказани (например за отношението на автора към ЛГБТИ+ хората).

Сексуалните престъпления срещу деца. Институционална и обществена слепота

В предишната си статия Теодора Станимирова представи данни, разкриващи системното безсилие на институциите спрямо сексуалните злоупотреби с деца. В продължението на темата Теодора разговаря с експерти, за да разбере каква е реалната ангажираност на обществото и институциите – отвъд популизма.

По същество

Въпреки структурните си проблеми книгата като цяло е увлекателно четиво, написано с интелигентност и чувство за хумор. Интелигентността обаче не трябва да се бърка с коректност по отношение на фактите, нито с обща култура. Характерно за мисленето на Ален Симеонов е идентифицирането на фактите със собствената му представа за тях. Като почнем от убедеността му (на което е посветена цяла глава) в недоказаната хипотеза, че Епстийн не се е самоубил, и се стигне до твърдението, че „смятаме“ Южна Корея (тук потребителите на Samsung и феновете на кей-поп музиката повдигат вежди) и Нигерия за „тоталитарни и изостанали“.

Култ към личността

Ален Симеонов създава систематично и последователно култ към собствената си личност. Подобно на религиозен харизматичен водач, той разполага с конкретен разказ за полагането на основите на движението си, започващ така:

Един ден през лятото на 2020 г., разхождайки се с приятели из Банската градина в София, им разказах за социалния проект, който се зараждаше в главата ми.

За изграждането на култа към себе си Симеонов има образец и не го крие – Максим Марцинкевич – Тесак, починал в затвора официално при самоубийство (авторът не поставя под съмнение, че е убит). Дори прилича на някои от снимките на идола си. Той предава без критична оценка факта, че в името на организацията на Тесак „Формат 18“ се съдържат кодираните инициали на името на Адолф Хитлер (А – първата буква от латинската азбука, H – осмата). Самият Ален Симеонов впрочем се е снимал с „Моята борба“ в свое видео с „лов на педофили“. Той пише:

От Тесак осъзнах важността на разпознаваемите символи за една идея: лого, жест, цветова комбинация, посрещане, здрависване. Така се родиха и моите символи – пречупеният палец, който показвам в почти всяко видео, и репликата „Здравейте, скъпи любители на учтивия натиск“.

Пречупеният палец се превърна в същинска енигма за гледалите мои разследвания, а с него ме поздравяват стотици тийнейджъри и хора по улиците […] Този символ идва от Тесак […] Превръща този палец в знак на лова – символ, който заимствах, за да продължа посланието му в един нов контекст.

Важни аспекти на култа, който Ален Симеонов създава към себе си, са, че той по дефиниция винаги е прав и че трябва да е най-отгоре. На едно място в книгата не скрива разочарованието си, че арестът на Бойко Борисов „ще засенчи“ (!) делото срещу 21 „извратеняци“, арестувани благодарение на дейността му. Като че единственият човек, към когото отношението в книгата е почти като към равен, е влогърът Станислав Цанов, топло наричан от него Стан.

Педофилията, срещу която се протестира, и педофилията, за която се мълчи

Гражданският гняв, изразяващ се в протести срещу насилието над деца и срещу неработещата държава, е абсолютно оправдан. Но е важно, когато си отваряме очите за едно, да не ги затваряме за друго. От Светла Енчева.

С други някогашни съратници отношенията му се развалят. Един от тях е учителят по история Александър Александров от националистическата организация „Общностъ с идеалъ“, когото упреква, че се е опитвал да го въвлече в политическа дейност, а Симеонов държи на партийната си необвързаност. Друг е Васил Димитров от „Младите срещу системата“, който според автора е започнал да събира пари за каузата („лов на педофили“) без негово знание и съгласие.

Отношение към хората

Ален Симеонов раздава оценки на хората от позицията на върховна инстанция. Принципът на оценяването впрочем е доста прост – които го харесват и споделят каузата му, са добри. Които са критични към него и/или каузата, дори ако са добронамерени, са лоши.

Например Радослав Стоянов от БХК и журналистката Пролет Велкова са наречени „безсрамни продажници“, Мария Йотова от NOVA е упрекната за „самочувствието“ си, понеже го е посъветвала да прекрати каузата си, защото заради него „можело някой някъде да убие гей, смятайки го за педофил“. На други, които не са съгласни с него, се подиграва на външния вид или говори за тях снизходително („женица“, „хорица“ и пр.).

Одобряващите Симеонов и каузата му пък са „достойни“ и носители на куп положителни качества.

Що се отнася до отношението към „обектите на лов“, то не е като към хора.

И речникът, който използва по техен адрес, е дехуманизиращ – не само квалификации като „извратеняк“ и „дегенерат“, а и отричащи човешкото у тях определения като „човекоподобно“, „хищник“ и пр. Да не забравяме името на каузата на Ален Симеонов (което впрочем не присъства в книгата, освен в един медиен материал, намерил място в нея) – „Педофилските животи нямат значение“.

Освен това на всеки „уловен“ се измисля някакво унизително прозвище – „невинен лизач“, „любопитно лайно“, „напикан кросдресър“, „миришещия Митко“ и т.н. Всичко звучи много забавно за последователите, повечето от които са деца. И които се формират като личности с убеждението, че има хора, които не са хора, и затова е не само нормално, а и необходимо да се саморазправяме с тях.

Наистина ли им пука за децата?

Светла Енчева с паралел между два нашумели случая, в които са намесени деца. В единия ги намесиха от „голяма загриженост“, но без реална нужда, институциите и политиците, а в другия пак институциите и политиците си затварят очите за истинския проблем – насилие над малко дете от учителката му.

Същевременно Ален Симеонов отрича обвиненията, които някои от уловените са повдигнали срещу него – за телесни повреди или за откраднати вещи. Но да не забравяме, че една от целите на книгата е да послужи за защитата му. Склонен е обаче да омаловажава други форми на насилие, например шамари, бръснене на глава и пр. – според него „педофилите“ по дефиниция заслужават подобно отношение и е проява на наглост, ако решат да си търсят правата.

Възгледи

Ален Симеонов избягва да се идентифицира с определена политическа идеология, макар между другото да споделя, че като 16-годишен е бил разпитван в СДВР, защото посещавал „родолюбиви мероприятия“ (за да станат тези мероприятия интересни на МВР, „родолюбивостта“ им ще да е била доста екстремна). Това не е случайно – той смята, че ако каузата му не е ограничена в рамките на национализма, тя ще е по-привлекателна за хора с различни разбирания.

Възгледите му не могат да се определят и като проруски – за „Възраждане“ презрително се изказва, че е смятал привържениците на тази партия за „комунисти и соцносталгици“. Макар да нарича „делото“ си „полезно, патриотично и родолюбиво“ и да цитира политзатворника антикомунист Илия Минев („Ти какво пожертва, за да има и утре България?“), той по-често представя действията си като форма на активност на гражданското общество. А към края на книгата заявява, че „ловът е наднационална кауза на цялото общество“. Твърди, че дейността му не е против институциите, а напротив – целта е „да ги накараме да работят“.

Свеждането на „борбата с педофилията“ до „лов“ обаче изхожда от доста ограничена представа за сексуалните злоупотреби с деца. Тя е насочена само срещу търсещите интимни контакти по интернет с полово зрели малолетни и непълнолетни. Но от вниманието на „ловците на педофили“ напълно са изпаднали теми като сексуалното насилие над малки деца (помните ли случая с учителката в детска градина в Каблешково?), в семейството, в институции. Последните се явяват тема в книгата само веднъж, когато авторът преразказва думи на друг човек, директор на център за настаняване на деца от семеен тип (ЦНСТ), според когото „множество неправителствени организации получават милиони, като се възползват от тези изоставени деца, създавайки подобни ЦНСТ-та“. Тоест за ситуацията на децата в домовете са виновни лошите НПО-та.

Симеонов категорично се противопоставя на предложенията да стане част от „Възраждане“. Твърди, че на организирани от партията протести, на които е присъствал, е имало и „нерези“, които са му признавали за свои сексуални контакти с „малки момичета и тийнейджърки“. Един вид, и във „Възраждане“ има педофили. И въпреки приемането на закона за регистъра на педофилите той е недоволен, че от „Възраждане“ са политизирали темата и че вносителят му в парламента Петър Петров „приписва заслуги на партията си“. Според Ален Симеонов реалните заслуги са си негови и на съратниците му, внесли становища в НС. Изразява разочарование, че регистърът не е публичен (при завършването на книгата той, изглежда, още не е станал такъв).

На позорния стълб

Темата „педофилия“ е достатъчно токсична, за да накара политиците да изглеждат единодушни. Така без особени колебания парламентът направи част от „регистъра на педофилите“ публична. Но предпазва ли това децата, или просто превръща страха в удобен политически инструмент? От Светла Енчева.

Като изключим акциите за „лов на педофили“, една от най-разпознаваемите публични прояви на Симеонов е участието му в протеста срещу белгийския филм „Близо“. В книгата си обаче той изразява съжаление за ролята си в събитието, от което са се възползвали от „Възраждане“. И добавя:

Да не говорим, че подобно псевдопротестиране срещу филми поначало не се различава от цензурните и заглушителни практики върху киното в Съветския съюз.

Симеонов не се вписва в националистическите клишета и с възгледа си, че най-добре ще е наркотиците да се легализират. Той смята така:

Дилърите и наркоупотребяващите не са престъпниците, за които законът ги представя, а по-скоро самият закон ги прави престъпници.

Колко сме Ален Симеонов?

Важно място в книгата „Училище за ловци на педофили“ заемат отношенията на автора с институции и техни представители. Той е водил разговори с членове на всички парламентарни групи и ги изброява поименно. Особено внимание заслужават описанията на контактите му с полицията и прокуратурата, които хем го задържат и повдигат обвинения срещу него, хем го хвалят и потупват по рамото (тогавашната ръководителка на Софийската районна прокуратура Невена Зартова например публично изказва благодарност за видеозаписите, в резултат на които са арестувани 21 души). А понякога тези действия вършат едни и същи хора.

Симеонов твърди, че служител на полицията „с отличаваща се националистическа позиция“ и негови колеги са го вербували да лови дилъри на наркотици и да им предава информация за тях, и че се е занимавал и с това известно време.

Но Ален Симеонов се радва на симпатия и подкрепа не само от представители на институции, а и от деца и възрастни с разнообразни ценности и политически убеждения.

Често пъти децата, играещи ролята на „примамка“ в „лова“, правят това със съгласието на родителите си, които са убедени, че по този начин допринасят за борбата срещу сексуалната злоупотреба с малолетни и непълнолетни. Каузата „да хващаме лошите и да караме институциите да си вършат работата“ действително звучи достойно за душата.

За одобрението на „лова на педофили“ допринася и фактът, че е трудно залавяните мъже да не предизвикат антипатия, ако не и по-остри негативни емоции. Съдържанието на чатовете им с представящите се за 13-годишни деца е възмутително и често пъти откровено гнусно. Мнозина биха поискали „такива да си получат заслуженото“.

Новите тимуровчета

Статията на Светла Енчева е провокирана от няколко случая на самоинициативи, при които деца раздават „правосъдие“ по собствена преценка. Особено тревожни са медийното им героизиране и подкрепата от…

В България разбирането за ценността на човешкия живот и човешкото достойнство не е широко разпространено.

В училище се набива в главите на децата колко е важна саможертвата за родината, но не и че всички хора са еднакво хора. Тук дори не става дума за емпатия (която също е дефицитна по нашите ширини), а за базисен рефлекс за основите на съвременната демокрация. Заради същия този рефлекс например Норвегия не предприе популистки мерки срещу масовия убиец Андеш Брайвик.

Ако смятаме, че дадени човешки същества са изроди, нехора, защото правят лоши неща и/или притежават отблъскващи характеристики, тогава Ален Симеонов е прав. Което пък отваря широко вратата за саморазправа с „нехората“. А тя лесно може да стигне до линч и до физическо унищожение. Това е радикализация, маскирана като гражданска активност.

Но ако сме отворили кутията на Пандора и с лека ръка обявяваме някои хора за изроди, чийто живот и достойнство нямат значение, в следващия момент „изродите“ може да се окажем ние, както вече са разбрали от собствен опит децата, били Кузев до смърт.

А може би го е разбрал дори и самият Ален Симеонов.

[$] LWN.net Weekly Edition for October 1, 2026

Post Syndicated from jzb original https://lwn.net/Articles/1096293/

Inside this week’s LWN.net Weekly Edition:

  • Front: PostgreSQL and the kernel; Rust on the GPU; KDE Plasma; C and memory safety; Rust radio; KDE funding; Chromium development.
  • Briefs: File-notification attacks; Kernel report; TAB election; F-Droid 2.0; Firefox 157.0; GDB 18.1; Git v2.56.0; Quotes; …
  • Announcements: Newsletters, conferences, security updates, patches, and more.

Amazon S3 Tables now support all Apache Iceberg V3 data types

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/amazon-s3-tables-now-support-all-apache-iceberg-v3-data-types/

Amazon S3 Tables now support all data types in the Apache Iceberg V3 specification. You can create V3 tables or upgrade existing V2 tables to take advantage of V3 features like deletion vectors, row lineage, and new data types such as variant, nanosecond timestamps, unknown, geometry, and geography.

Apache Iceberg has become the open standard for managing large analytics datasets. It lets you manage petabyte-scale tables with features like schema evolution, hidden partitioning, and time travel queries, while keeping your data in open Parquet files in data lakes on object storage like Amazon S3. Amazon S3 Tables offer storage purpose-built to keep Iceberg tables performant and cost-effective as they grow, with fully managed features like automatic compaction, maintenance, replication, and Intelligent-Tiering.

Teams running analytics on Apache Iceberg V2 tables often hit the same limits as their data grows. A compliance request to delete 50,000 user records from a 2-billion-row table leaves behind positional delete files that slow queries until compaction runs. Semi-structured events land as JSON strings that every query has to parse. Geospatial coordinates and nanosecond-precision timestamps get encoded as strings or integers. Each workaround adds storage cost, query latency, and pipeline code. With V3, Iceberg solves these challenges by offering native support for semi-structured and geospatial data, faster row-level operations, and built-in row lineage for data governance.

Starting today, Amazon S3 Tables support all V3 data types, including variant, nanosecond timestamps, geometry, geography, and unknown, along with deletion vectors and row lineage. You can create new V3 tables or upgrade existing V2 tables in place, and S3 Tables continue to run compaction and maintenance for you.

Apache Iceberg V3

V3 is the latest version of the Iceberg specification. Among its many improvements, V3 introduces capabilities that address the most common pain points in V2. This includes:

Deletion vectors replace V2’s positional delete files with a compact binary format. That 50,000-row compliance delete now writes a single deletion vector file instead of thousands of small deletes, significantly reducing compaction time and delete file overhead.

Row lineage adds _row_id and _last_updated_sequence_number to each record automatically. Your downstream pipelines can query these fields to find changed rows without scanning the full table.

New data types let you store semi-structured, geospatial, and nanosecond-precision data natively instead of encoding it as strings or integers:

  • Nanosecond timestamp(tz) for nanosecond-precision timestamps
  • Geometry and geography for geospatial data
  • Unknown for columns with no known type

Variant data type stores semi-structured data in columnar format. During writes, the engine shreds variant data into hidden columns and collects statistics. At query time, those statistics enable file pruning that significantly reduces I/O compared to parsing JSON strings.

The following sections walk through how to use these V3 capabilities in practice, with examples that show how to create tables, work with the new data types, and manage data at scale.

Getting started

A retail analytics team tracks user behavior across web and mobile apps. Each event has a different structure: page views include URLs and duration, purchases include items and amounts, and searches include query terms and result counts. With V3’s variant type, you store all event shapes in one table without predefined schemas:

CREATE TABLE my_catalog.namespace.clickstream (
  event_id bigint,
  event_time timestamp,
  user_id string,
  payload variant
)
USING iceberg
TBLPROPERTIES ('format-version' = '3')

Insert events with different payload shapes without worrying about schema evolution:

INSERT INTO my_catalog.namespace.clickstream VALUES
  (1, current_timestamp(), 'user-42',
   PARSE_JSON('{"action": "purchase", "amount": 99.99, "items": ["laptop_stand"]}')),
  (2, current_timestamp(), 'user-17',
   PARSE_JSON('{"action": "page_view", "url": "/products/webcam", "duration_ms": 4200}'));

Now query the variant column directly, without PARSE_JSON at read time. With Amazon EMR Spark, use variant_get:

SELECT
  event_id,
  user_id,
  variant_get(payload, '$.action', 'string') AS action,
  variant_get(payload, '$.amount', 'double') AS amount
FROM my_catalog.namespace.clickstream
WHERE variant_get(payload, '$.action', 'string') = 'purchase'
  AND variant_get(payload, '$.amount', 'double') > 50.00

To enable deletion vectors for write operations, configure merge-on-read mode:

ALTER TABLE my_catalog.namespace.clickstream
SET TBLPROPERTIES (
  'write.delete.mode' = 'merge-on-read',
  'write.update.mode' = 'merge-on-read',
  'write.merge.mode' = 'merge-on-read'
)

Now when you run a compliance delete, V3 writes a small deletion vector instead of rewriting data files:

DELETE FROM my_catalog.namespace.clickstream
WHERE user_id = 'user-42'

S3 Tables compaction handles these deletion vector files automatically on the next maintenance cycle.

Upgrading from V2

AWS provides backwards compatibility for both versions to minimize disruption during migration to V3. Existing V2 readers continue to work on upgraded tables until you’re ready to fully adopt V3 features. For more details, see the S3 Tables Iceberg V3 documentation.

Upgrade an existing table atomically without rewriting data:

ALTER TABLE my_catalog.namespace.existing_table
SET TBLPROPERTIES ('format-version' = '3')

On the next compaction cycle, S3 Tables remove old V2 delete files. New modifications use deletion vectors automatically. Row lineage fields initialize on the first data modification after the upgrade.

This is a one-way operation. The Apache Iceberg specification does not support downgrading from V3 to V2. Verify that all engines accessing the table support V3 before upgrading.

Using row lineage for incremental pipelines

After your table has V3 data, use row lineage to build efficient incremental pipelines:

SELECT *, _row_id, _last_updated_sequence_number
FROM my_catalog.namespace.clickstream
WHERE _last_updated_sequence_number > 42

This returns only rows modified after sequence number 42. Your downstream jobs can checkpoint this value and process only new changes on each run, instead of scanning the full table.

Compatibility across AWS analytics services

AWS offers the broadest native Apache Iceberg support of any major cloud provider, with Iceberg-compatible services at every layer of the data stack: ingestion, storage, catalog, and analytics. You can store and automatically optimize V3 tables in Amazon S3 Tables, write data with Amazon EMR Spark, integrate and manage data with AWS Glue, and run analytics with Amazon Redshift. To learn more about AWS analytics support for V3, see the Apache Iceberg on AWS prescriptive guidance.

Both S3 Tables and AWS Glue Data Catalog support the Iceberg REST Catalog (IRC) API, enabling interoperability across engines regardless of the catalog endpoint.

Things to know

  • S3 Tables compaction fully supports V3 deletion vector files and preserves row lineage metadata.
  • The new V3 data types (variant, nanosecond timestamps, geometry, geography, and unknown) require an engine built on Apache Spark 4.0 or later, such as AWS Glue 6.0 or later, or Amazon EMR release 8.1 or later.
  • You can create V3 tables from the Amazon S3 console, AWS CLI, or any engine that supports the Iceberg REST Catalog API.
  • The new V3 data types are supported only for tables that use the Parquet file format (not ORC or Avro).
  • Columns of type variant, geometry, geography, or nanosecond timestamp can’t be included in a table’s sort order for compaction. Tables containing these columns still compact under the sort and Z-order strategies when the sort order uses columns of other types.

Now available

Amazon S3 Tables support for all Apache Iceberg V3 data types is now available in all AWS Regions where S3 Tables are supported. Apache Iceberg V3 support is available at no additional charge; standard S3 Tables pricing applies.

To get started, visit the Amazon S3 Tables documentation or create a table bucket from the Amazon S3 console. If you want to call APIs, search documentation, find regional availability, and check troubleshooting about this feature, try using the AWS MCP Server and plugins with your preferred AI tool. Send feedback to AWS re:Post or through your usual AWS Support contacts.

– Daniel Abib

Gigabyte TRX50 AERO D Motherboard Review

Post Syndicated from Ryan Smith original https://www.servethehome.com/gigabyte-trx50-aero-d-motherboard-review/

Today we are taking a look at Gigabyte’s TRX50 AERO D motherboard. Aimed at the high-end desktop market, Gigabyte has designed the AERO D to be a basic but effective pairing for AMD’s Threadripper 9000 processors

The post Gigabyte TRX50 AERO D Motherboard Review appeared first on ServeTheHome.

Amazon S3 Vectors now supports metadata pre-filtering for higher recall on filtered searches

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/amazon-s3-vectors-now-supports-metadata-pre-filtering-for-higher-recall-on-filtered-searches/

Today, we’re announcing metadata pre-filtering for Amazon S3 Vectors, which delivers higher recall on filtered queries by evaluating your metadata filter before the similarity search. You can filter on attributes such as tenant, category, status, or time, and pre-filtering adds prefix matching with $startsWith for paths, URLs, and hierarchical keys. Each vector carries up to 2 KB of filterable metadata, and a single query supports up to 100 filter constraints. There is no additional cost, no re-ingestion, and no change to your queries.

Most applications never search a whole index. They search the part of it that belongs to a particular user, account, or category, and they express that scope as a metadata filter. Semantic search, retrieval-augmented generation (RAG), and agentic applications all need the same thing from a filtered query: a similarity search that covers the vectors matching the filter, and returns the closest of them. With pre-filtering, a filtered query returns more of the relevant matches your index contains, giving you higher recall on filtered searches.

Common use cases

Pre-filtering applies wherever results have to be both relevant and correctly scoped:

  • Legal and professional services: A law firm or e-discovery platform searches documents scoped to a single client, and with $startsWith narrows further by matter number, folder path, or document ID prefix. A single client is a small share of a firm-wide archive, and filters this narrow are where pre-filtering improves recall most.
  • Financial services: An investment research platform searches analyst notes, filings, and call transcripts scoped by issuer, document type, and publication date.
  • Media and entertainment: A streaming service filters by content rating and regional licensing before the semantic search, finding similar titles restricted to G and PG content licensed in one territory.
  • Agentic applications: An agent working within a user’s session filters on fields such as owner, document set, and timestamp so its searches cover the material relevant to the task at hand. Higher recall means more of that material reaches the agent, which improves task reliability

How pre-filtering works

Each vector in an S3 Vectors index can carry application-defined metadata, and a query can filter on those fields.

Every vector index has an index mode. On an index whose index mode is ENHANCED, S3 Vectors resolves your filter first, then searches only the vectors that match. On an index whose index mode is CLASSIC, S3 Vectors performs the vector search and filter evaluation in tandem, validating each candidate vector against your filter as it searches. Existing indexes use CLASSIC until you update them.

Consider a support knowledge base of 8 million tickets, where an agent searches one customer’s history for a recurring error. If that customer accounts for 400 of those tickets, resolving customer_id first means the similarity search runs across all 400 of them, so the agent sees that customer’s prior occurrences. Before the index was updated, the same query drew its candidates from the full 8 million, and the result set contained fewer of that customer’s matching tickets.

On highly selective filters, pre-filtering returns up to 5x more of the matching vectors than the same query returned before on CLASSIC indexes.

Getting started

Before you start, make sure your IAM policy grants permissions for the new actions.

You can get started in three steps. The walkthrough below builds a small product-catalog index and runs a selective filter against it, the same pattern you would use for a multi-tenant RAG store or a document search scoped to one client.

First, create a vector index:

aws s3vectors create-index \
  --index-name product-catalog \
  --vector-bucket-name my-vector-bucket \
  --dimension 1536 \
  --distance-metric cosine

The dimension must match the output size of your embedding model, and distance-metric should match how that model was trained (cosine is common for text embeddings). Second, write vectors with the PutVectors API, attaching up to 2 KB of filterable metadata to each vector:

aws s3vectors put-vectors \
  --index-name product-catalog \
  --vector-bucket-name my-vector-bucket \
  --vectors '[{
    "key": "doc-001",
    "data": {"float32": [0.1, 0.2, 0.3, ...]},
    "metadata": {
      "tenant_id": "t-10428",
      "category": "legal",
      "created_date": "2026-03-15",
      "active": true
    }
  }]'

Each vector carries the attributes your application filters on. In this example, tenant_id scopes results to a single customer, category narrows by document type, created_date records when the document was created, and active is a boolean flag. By default every metadata field is filterable, so you can query on any of them without declaring a schema up front.

Third, run a filtered similarity query with the QueryVectors API. The filter uses a compact JSON syntax where a bare key-value pair is an equality match, and operators such as $and, $or, and $gt combine or refine conditions. Pass --return-metadata so the query returns each vector’s metadata:

aws s3vectors query-vectors \
  --index-name product-catalog \
  --vector-bucket-name my-vector-bucket \
  --query-vector '{"float32": [0.1, 0.2, 0.3, ...]}' \
  --top-k 50 \
  --return-metadata \
  --filter '{"$and": [
    {"tenant_id": "t-10428"},
    {"category": "legal"},
    {"active": true}
  ]}'

The expected result is a single vector, doc-001, the only one matching all three filter conditions (tenant_id, category, and active):

{
  "vectors": [
    {
      "distance": 0.9717477560043335,
      "key": "doc-001",
      "metadata": {
        "tenant_id": "t-10428",
        "category": "legal",
        "created_date": "2026-03-15",
        "active": true
      }
    }
  ],
  "distanceMetric": "cosine"
}

S3 Vectors first narrows the search space to vectors matching all three filter conditions, then returns the 50 most similar vectors from that subset. Because the filter is applied before the search, those results are drawn from across all the vectors that match it.

Prefix matching with $startsWith

Pre-filtering adds a prefix match operator for filtering on paths, URLs, and hierarchical keys. A document store that encodes case and folder structure into a document ID can scope a search to a subtree in one condition:

--filter '{"$startsWith": {"document_id": "matter-4417/exhibits/"}}'

$startsWith joins the existing operators: equality, numeric range, set membership, existence checks, and boolean logic with $and and $or.

Turning on pre-filtering for existing indexes

Call UpdateIndexMode on an existing index to turn on pre-filtering:

aws s3vectors update-index-mode \
  --vector-bucket-name my-vector-bucket \
  --index-name product-catalog \
  --index-mode ENHANCED

Pre-filtering takes effect in place. Your existing vectors are not re-ingested, your queries do not change, and the new filter operators are available immediately.

Here is the difference on the same index and the same query. Before the update, a query scoped to one tenant returns two of the ten results requested:

aws s3vectors query-vectors \
  --vector-bucket-name my-vector-bucket \
  --index-name product-catalog \
  --query-vector '{"float32": [0.1, 0.2, 0.3, ...]}' \
  --top-k 10 \
  --return-metadata \
  --filter '{"tenant_id": "t-10428"}'
{
  "vectors": [
    { "key": "doc-114", "distance": 0.41 },
    { "key": "doc-322", "distance": 0.55 }
  ],
  "distanceMetric": "cosine"
}

After the update, the same query returns a full result set drawn from across that tenant’s documents:

{
  "vectors": [
    { "key": "doc-018", "distance": 0.09 },
    { "key": "doc-207", "distance": 0.13 },
    { "key": "doc-114", "distance": 0.41 },
    ... 7 more
  ],
  "distanceMetric": "cosine"
}

Rolling out across your indexes

Once you have validated pre-filtering on an index, set the default index mode on the vector bucket so that new indexes use ENHANCED without a follow-up call:

aws s3vectors put-vector-bucket-default-index-mode \
  --vector-bucket-name my-vector-bucket \
  --default-index-mode ENHANCED

To bring the rest of your existing indexes across, list them and check the index mode on each one, then call UpdateIndexMode on the ones still using CLASSIC:

aws s3vectors list-indexes \
  --vector-bucket-name my-vector-bucket

aws s3vectors get-index \
  --vector-bucket-name my-vector-bucket \
  --index-name product-catalog

Things to know 

  • Indexes created in vector buckets created on or after September 30, 2026 use index mode ENHANCED. Indexes in buckets that existed before that date use CLASSIC until you set the bucket default, including indexes created in those buckets afterward.
  • A single query supports up to 100 filter constraints, counted per value the filter evaluates. If a query exceeds that, you can usually consolidate the filter, replacing a 300-value $in over legal cases with a single caseId field, for example, or split it into smaller queries, run them in parallel, and merge the results by distance.

Get started today

Metadata pre-filtering is available at no additional cost in all commercial AWS Regions where Amazon S3 Vectors is available, and in the AWS China Regions. You pay standard S3 Vectors pricing for storage, PUT requests, and queries. For full pricing details, visit the Amazon S3 pricing page. For regional availability, visit Amazon S3 Vectors Regions and quotas.

Whether you’re scoping a RAG application to one tenant, scoping an agent’s searches to one user’s documents, or narrowing a catalog search to a licensing window, pre-filtering lets you apply those filters without trading away recall. To learn more and get started, visit the Amazon S3 Vectors documentation. Send feedback to AWS re:Post for S3 or through your usual AWS Support contacts.

— Daniel Abib

Running production experiments with AWS AppConfig experimentation

Post Syndicated from Aparna Krishnamoorthy original https://aws.amazon.com/blogs/devops/running-production-experiments-with-aws-appconfig-experimentation/

A redesigned checkout button is meant to lift sales. A longer cache time to live (TTL) is meant to cut backend load. But until you test a change against real production traffic, decisions come down to intuition and whoever argues hardest, not evidence. With AWS AppConfig experimentation, you can make data-driven calls instead: using A/B testing, you expose a change to a slice of real users, measure what happens, and let the results decide. It’s part of AWS AppConfig, a capability of AWS Systems Manager, so there’s no separate platform to stand up.

Testing in a development environment confirms a change works, but not how real users or production workloads respond. Releasing to everyone at once answers that but exposes every user to any negative effects, such as broken checkout flows or degraded performance. An experiment is the middle ground: real production traffic, but only a controlled slice of it.

AWS AppConfig experimentation builds on AWS AppConfig feature flags: you define a hypothesis and eligible audience, and a feature flag assigns each participant to the control or a treatment. The AWS AppConfig Agent delivers the right value to each participant, and you keep full control of your data, you join treatment-assignment records with your existing analytics platform.

In this post, you build the following experiments:

  • A frontend experiment that tests a redesigned Add to cart button
  • A backend experiment that compares cache TTL settings in a service running on Amazon Elastic Container Service (Amazon ECS)

You also learn how to record treatment assignments, monitor application health, analyze the results, and promote the winning treatment.

Prerequisites

This post assumes you’ve completed the experimentation prerequisites in the AWS AppConfig User Guide: a feature flag deployed to your environment, the AWS AppConfig Agent installed and configured in your compute environment (including the IAM permissions it needs), and experiment assignment logging enabled on the Agent. To follow the examples here, you also need:

1. AWS Command Line Interface (AWS CLI) 2.35.12 or later, configured with credentials for the account and Region you use. Verify your version with aws –version.

2. A data warehouse or analytics destination for assignment and outcomes data. This post uses Amazon Athena over data in Amazon S3, but AWS AppConfig experimentation works with Amazon CloudWatch or any warehouse you already use, such as Amazon Redshift or Snowflake.

Architecture Overview

AWS AppConfig experimentation adds A/B testing on top of the AWS AppConfig workflow you already use. The control plane lives in AWS AppConfig, treatments are delivered at the edge by the AWS AppConfig Agent, and analysis stays in your existing data warehouse. AWS AppConfig itself provides real-time aggregate traffic metrics; it doesn’t own results analytics, which keeps your metric definitions and data under your control.

The flow looks like this:

AppConfig Experimentation Architecture

Figure 1: AWS AppConfig experimentation — the control plane in AWS AppConfig plus three runtime responsibilities (delivery, measurement, and safety), with the Agent’s assignment log reaching Amazon S3 through Amazon CloudWatch Logs and Amazon Data Firehose 

Beyond the control plane in AWS AppConfig, where you define the experiment and its treatments, three things happen at runtime:

  • Delivery (the data plane). The AWS AppConfig Agent retrieves the feature flag configuration from AWS AppConfig, caches it locally, and asynchronously polls for updates. Your application asks the agent for a flag over the local HTTP endpoint (http://localhost:2772/...), passing an entity Id and any relevant request context. The agent returns the assigned treatment. The Agent returns the same treatment for the same entity for the life of the run, so a user or instance never flips treatments mid-experiment.
  • Measurement. Two data sets meet here. The first is treatment assignments. The Agent writes one JSON record per assignment to standard error. Your log driver ships that record to Amazon CloudWatch Logs, and a subscription filter (matched on the record type) forwards it through Amazon Data Firehose into Amazon S3. The second is your metric events — conversions, latency, cost, and errors — which keep flowing through whatever pipeline you already run.

    Note: We recommend not using sensitive information such as personally identifiable information (PII) for the entity ID, the Agent logs it verbatim. If you must, hash or pseudonymize it identically in both your assignment and metric data – the entity ID is the key that joins the two.
  • Safety. Amazon CloudWatch alarms watch operational and experiment metrics. If an alarm fires during a run, you stop the run, which ends exposure and returns users to the deployed configuration.

One mechanism serves a frontend team, an AI team, and a backend team, each keeping its own metrics and tooling.

Example 1 — Frontend UI Experiment

Scenario. Your team believes a redesigned “Add to cart” button will lift conversion, but you only have a hypothesis. You want to expose it to a slice of production traffic and measure real behavior.

Create the experiment (console) 

The experiment definition ties an application, environment, configuration profile, and feature flag to a control and one or more treatments. Audience rules determine who is eligible, and launch criteria define what counts as success. In the AWS AppConfig console, choose Experiments, then Create experiment, and work through five steps. AI-assisted experiment design in the console can validate your setup against Amazon’s experimentation best practices, helping you catch design gaps before you start a run.

Step 1 — Document your hypothesis. Give the experiment a descriptive Experiment name (add-to-cart-redesign), state the Experiment hypothesis, and use Launch criteria to record the evidence required before you promote a winner — a minimum sample per treatment, the lift you’re looking for, and the guardrails that must not regress. Writing it down now is what makes the result interpretable weeks later, and Validate my hypothesis and launch criteria will review both before you continue. Select StoreFront as the Application name.

Figure 2: Documenting the hypothesis and launch criteria for the add-to-cart experiment


Step 2 — Specify target audience. Describe the audience, then build the rule. The Rule builder tab composes conditions from an attribute, an operator, and a value: $platform equals “web”, joined with And to $geo in [“USA”,”CAN”]. Sample blueprints offers pre-built rules to start from, and the Editor tab shows the same rule as an expression — the form to use if you later automate this:

(and 

  (eq $platform "web") 

  (in $geo ["USA","CAN"]) 

) 


Figure 3: Building the audience rule from two conditions 

That notation is an S-expression — a prefix, function-style form, (operator arg1 arg2 …). The notation is generic; AppConfig defines the operators and the $-prefixed attribute references, which are populated from the caller context your application sends. Here $geo is an attribute your application supplies — the visitor’s country, not an AWS Region.

Note: AWS AppConfig is Regional, so an experiment lives in one AWS Region — don’t use AWS Region as an audience attribute. Segment on caller properties (geography, platform, plan tier, app version); to test across Regions, replicate the experiment definition in each and measure independently.

Step 3 — Select experiment feature flag. Choose the Environment (prod), the Configuration profile holding the flag (Features), and the Feature flag itself (add_to_cart_button). The list shows flags already deployed to that environment.

Figure 4: Selecting the deployed feature flag the experiment will control


Step 4 — Add treatments. Describe the Control as your known-good baseline, confirm its Flag value is toggled ON, and under Attribute values set button_style to classic and button_color to #232F3E. The list includes every attribute the flag defines, including ones this experiment doesn’t vary.

Figure 5: The control treatment, serving the current button 

Then describe Treatment 1 the same way, setting button_style to prominent and button_color to #FF9900. Keep each treatment to a single change so the result stays interpretable. AppConfig allocates traffic evenly across treatments automatically — an even 50/50 here, which is also what maximizes statistical power. Advanced settings offers custom weights, but the even split is the recommended default.

Figure 6: The treatment variant and the even traffic split 

Step 5 — Review and complete. Check the summary and save. Users who aren’t assigned to the experiment continue to receive the default flag value deployed to their environment; only users in the control or a treatment are measured. AppConfig generates a treatment key for each treatment rather than deriving it from your description — it’s the value the Agent returns as _variant — and you use these keys later in treatment overrides and analysis queries.

Figure 7: The saved experiment definition, ready to start a run


Retrieve the treatment (Node.js) 


Your web tier asks the local AWS AppConfig Agent for the flag, passing the visitor identity as Entity-Id so the same visitor always gets the same experience, plus any context the audience rule needs. Request the flag by name with the flag parameter – if you request the whole configuration without it, no experiment assignment is recorded.

// Node.js 18 or later: fetch and Headers are globals, no imports needed. 


const AGENT = "http://localhost:2772"; 

const PATH = 

  "/applications/StoreFront/environments/prod/configurations/Features"; 


export async function getButtonTreatment(visitorId, geo) { 

  // Multiple context values are sent as repeated "Context" headers, 

  // so use a Headers object with append (an object literal would drop 

  // all but the last "Context" entry). 

  const headers = new Headers(); 

  headers.set("Entity-Id", visitorId); // consistent assignment for the run 

  headers.append("Context", "platform=web"); 

  headers.append("Context", `geo=${geo}`); 


  const res = await fetch(`${AGENT}${PATH}?flag=add_to_cart_button`, { 

    headers, 

  }); 


  // The request names a single flag, so the agent returns that flag’s 

  // object directly — there is no wrapper keyed by flag name: 

  // { "_variant": "__t1__", "enabled": true, 

  //   "button_style": "prominent", "button_color": "#FF9900" } 

  return await res.json(); 

}

Capture treatment assignments (AWS AppConfig Agent) 

The Agent logs each assignment for you – you don’t write the exposure-logging code. With EXPERIMENT_ASSIGNMENT_LOG_DESTINATION set to stderr, the Agent emits an assignment record the first time it assigns a visitor to a treatment, and that record’s timestamp is what makes clean post-exposure attribution possible later (see the Analyzing experiment results section). Your application’s job is narrower: keep producing the outcome data you already produce — add-to-cart clicks, checkouts, orders. The one thing to get right is the join key:as the Entity-Id, pass an identifier your outcomes dataset already carries — a customer ID, account ID, or session ID — so the records join with no change on your side.

# Amazon ECS, Amazon EKS, or Amazon EC2 - set this on the agent container 

# or host. To collect the files yourself, use a base directory instead of 

# "stderr", in the form file:/tmp/aws-appconfig/assignments/ 

EXPERIMENT_ASSIGNMENT_LOG_DESTINATION=stderr 


# AWS Lambda - set this on the function. The extension reads the same 

# setting under a prefixed name. 

AWS_APPCONFIG_EXTENSION_EXPERIMENT_ASSIGNMENT_LOG_DESTINATION=stderr 


# One record per assignment. Shown formatted for readability; the agent 

# writes it on a single line so log shippers treat it as one event. 

{ 

  "type": "AWS.AppConfig.TreatmentAssignment", 

  "timestamp": "2026-07-29T16:27:55Z", 

  "region": "us-east-1", 

  "accountId": "111122223333", 

  "applicationId": "dn32rvt", 

  "experimentDefinitionId": "uioedbc", 

  "experimentRunNumber": "5", 

  "treatmentKey": "__t1__", 

  "entityId": "visitor-8f2c" 

} 

Note: The Agent’s ordinary application logs go to the same place as the assignment records, so your forwarder must match on type. Forward everything and you also forward application logs alongside the assignments and break the schema downstream. 

Getting the assignment log from STDERR into Amazon S3 

Three hops take you from the Agent’s standard error to something you can query. The runtime ships STDERR to Amazon CloudWatch Logs, which AWS Lambda and Amazon ECS do for you. A subscription filter forwards only the assignment records. Amazon Data Firehose writes them to Amazon S3. The first hop needs no work, so these two commands are the whole pipeline for the frontend example:

# 1. Firehose stream that lands assignment records in Amazon S3. 

#    The three processors are the step people miss - see the note below. 

aws firehose create-delivery-stream \ 

  --delivery-stream-name experiment-assignments \ 

  --delivery-stream-type DirectPut \ 

  --extended-s3-destination-configuration '{ 

    "RoleARN":   "arn:aws:iam::111122223333:role/FirehoseToS3", 

    "BucketARN": "arn:aws:s3:::my-experiment-data", 

    "Prefix":    "assignments/", 

    "ProcessingConfiguration": { 

      "Enabled": true, 

      "Processors": [ 

        {"Type": "Decompression", 

         "Parameters": [{"ParameterName": "CompressionFormat", 

                         "ParameterValue": "GZIP"}]}, 

        {"Type": "CloudWatchLogProcessing", 

         "Parameters": [{"ParameterName": "DataMessageExtraction", 

                         "ParameterValue": "true"}]}, 

        {"Type": "AppendDelimiterToRecord"} 

      ] 

    } 

  }' 


# 2. Forward only assignment records from the agent’s log group to that stream. 

aws logs put-subscription-filter \ 

  --log-group-name "/ecs/storefront" \ 

  --filter-name "appconfig-treatment-assignments" \ 

  --filter-pattern '{ $.type = "AWS.AppConfig.TreatmentAssignment" }' \ 

  --destination-arn \ 

    "arn:aws:firehose:us-east-1:111122223333:deliverystream/experiment-assignments" \ 

  --role-arn "arn:aws:iam::111122223333:role/CWLtoFirehose" 


Why the processors matter. CloudWatch Logs doesn’t forward events one at a time — it batches them, gzips each batch, and wraps it in an envelope. With no processing configured, your S3 objects hold compressed JSON, with each assignment record buried as an escaped string inside logEvents[].message.

Three built-in processors undo that. Decompression unzips the batch, CloudWatchLogProcessing with DataMessageExtraction discards the envelope and keeps only the message contents, and AppendDelimiterToRecord puts a newline between records so each lands on its own line. What arrives in Amazon S3 is then exactly the JSON the Agent emitted, one record per row. Leave Firehose compression off, because CloudWatch Logs has already gzipped the payload on the way in. To store Parquet, turn on Firehose data format conversion — it needs decompression enabled too.

Check it before you ramp. Treatment-assignment overrides produce no assignment records (overridden entities would pollute your results), so the 0% window can’t exercise this pipeline. Ramp to a small exposure instead, 1% is sufficient, let real assignments flow, and confirm a record lands under s3://my-experiment-data/assignments/. If the object is gzipped or the record is nested under logEvents, the processors are not configured correctly, and the analysis query later in this post will return nothing. Fix that before you ramp any further.

Amazon ECS without CloudWatch Logs. You can also skip the middle hop entirely. Run FireLens with Fluent Bit as the task’s log router, filter on the same type field, and write straight to Amazon S3. That is fewer moving parts and no envelope to unwrap, in exchange for owning the Fluent Bit configuration yourself.

Either route ends the same way: point an AWS Glue table at the S3 prefix, using the fields from the sample record above. That table is the treatment_assignments source the query in Analyzing experiment results reads, and joining it to your business data is then an ordinary SQL join on the identifier both sides already share. One naming detail to watch when you write that table definition: timestamp is a reserved word in Athena DDL, so the column has to be backtick-quoted there. Queries against the table need no quoting.

The same setup works for AI experiments. Prompt text is configuration rather than code, so a system prompt and its model parameters can live in flag attributes and be varied exactly like the button styling above — no redeploy to reword a prompt. Key the assignment on a session ID so a single conversation doesn’t switch prompts mid-thread, and treat token cost and latency as first-class guardrails, since a “better” prompt that quietly doubles spend isn’t a win.

Example 2 — Backend Cache TTL Experiment

Scenario. You suspect a longer cache TTL will cut database load without noticeably hurting freshness. This is a backend experiment, so the natural unit of assignment isn’t a user — it’s the service instance. Entity-Id set to the instance/task ID gives you stable, instance-level segmentation.

Example 1 used the console, which is the quickest way to get a first experiment running. This example uses the AWS CLI — the same definition expressed as JSON, which is what you’d reach for to script experiment creation or keep it in source control.

Create the experiment (CLI, instance-level segmentation) 

aws appconfig create-experiment-definition \ 

  --application-identifier "Catalog" \ 

  --environment-identifier "prod" \ 

  --configuration-profile-identifier "Features" \ 

  --flag-key "cache_config" \ 

  --name "cache-ttl-tuning" \ 

  --hypothesis "A longer cache TTL reduces DB load without hurting freshness" \ 

  --audience-rule '(eq $service "product-catalog")' \ 

  --control file://control.json \ 

  --treatments file://cache-treatments.json 

Define the variations (JSON) 

The control and each treatment are TreatmentInput objects: a FlagValue (the flag’s Enabled state plus its AttributeValues) and a Weight that sets traffic allocation. Where the console offered a plain Value field, the API takes a typed object — NumberValue for a number, StringValue for a string.

control.json:

{ 

  "Description": "Current 60s cache TTL (baseline)", 

  "Weight": 50.0, 

  "FlagValue": { "Enabled": true, "AttributeValues": { "ttl_seconds": { "NumberValue": 60 } } } 

} 


cache-treatments.json:

[ 

  { 

    "Description": "Increase cache TTL to 300s to reduce DB load", 

    "Weight": 50.0, 

    "FlagValue": { "Enabled": true, "AttributeValues": { "ttl_seconds": { "NumberValue": 300 } } } 

  } 

] 


Type numeric flag attributes deliberately. Define ttl_seconds as a number attribute on the feature flag with minimum and maximum constraints, and express it in whole seconds. AWS AppConfig validates attribute values when you save the configuration profile, so an out-of-range TTL fails there rather than in production.


Apply in an Amazon ECS service (Java / Spring Boot) 

The AWS AppConfig Agent runs as a sidecar container in the same Amazon ECS task and is reachable at localhost:2772. Use the Amazon ECS task ID as the Entity-Id so each instance holds a consistent treatment for the whole run.

@Component 

public class CacheConfigProvider { 


    private static final String AGENT_URL = 

        "http://localhost:2772/applications/Catalog/environments/prod" 

      + "/configurations/Features?flag=cache_config"; 


    private final HttpClient http = HttpClient.newHttpClient(); 

    private final String entityId = resolveTaskId(); // instance-level unit 


    public CacheConfig getCacheConfig() throws Exception { 

        HttpRequest request = HttpRequest.newBuilder() 

            .uri(URI.create(AGENT_URL)) 

            .header("Entity-Id", entityId) 

            .header("Context", "service=product-catalog") 

            .GET() 

            .build(); 


        HttpResponse<String> response = 

            http.send(request, HttpResponse.BodyHandlers.ofString()); 


        // single-flag request: no wrapper keyed by flag name 

        JsonNode flag = new ObjectMapper().readTree(response.body()); 


        String treatment = flag.get("_variant").asText(); 

        int ttl = flag.get("ttl_seconds").asInt(); 


        emitMetrics(entityId, treatment); // the agent logs the assignment 

        return new CacheConfig(ttl, treatment); 

    } 


    private String resolveTaskId() { 

        // ECS injects ECS_CONTAINER_METADATA_URI_V4. A GET on 

        // $ECS_CONTAINER_METADATA_URI_V4/task returns the task metadata, 

        // whose TaskARN ends with the task ID. 

        try { 

            String metadataUri = System.getenv("ECS_CONTAINER_METADATA_URI_V4"); 

            HttpRequest metadata = HttpRequest.newBuilder() 

                .uri(URI.create(metadataUri + "/task")) 

                .GET() 

                .build(); 

            String body = 

                http.send(metadata, HttpResponse.BodyHandlers.ofString()).body(); 

            String taskArn = 

                new ObjectMapper().readTree(body).get("TaskARN").asText(); 

            return taskArn.substring(taskArn.lastIndexOf('/') + 1); 

        } catch (Exception e) { 

            // Fail fast. A hard-coded fallback would hand every task the same 

            // Entity-Id, put the whole fleet in one treatment, and quietly 

            // invalidate the experiment. 

            throw new IllegalStateException("Could not resolve the ECS task ID", e); 

        } 

    } 

} 

Your service then emits its guardrail metrics tagged with the same entity_id, so you can compare the 60s and 300s TTL directly.

Configuring Safety Guardrails

An experiment is a production change, so treat it like one: define what “bad” looks like before you ramp. Two controls limit the damage: gradual exposure keeps the exposure small, and Amazon CloudWatch alarms that tell you when to stop the run.

Start safe, ramp gradually. Start every run at 0% audience exposure. At 0%, no traffic is assigned unless you add treatment-assignment overrides — specific entity IDs pinned to a treatment. Use that window to validate the treatment before any real users are exposed: confirm the flag renders the expected experience for each treatment (including the control), confirm your outcome metric logging works, and share the overrides with stakeholders for a preview. For the full validation checklist, see About running and monitoring an experiment.

One thing that window can’t cover: overrides produce no assignment records, so the assignment log pipeline is only exercised once real traffic is being assigned. Clear the overrides, increase exposure in small steps, and treat that first step as the point to confirm assignment records are landing in your warehouse before you ramp further. Watch metrics at each level so a regression hits a small blast radius, not your full audience. Treat overrides as a validation tool, not audience targeting — leave production segmentation to the audience rule.

# Start the run at 0% exposure to validate before exposing any production users. 

# Billing for the run begins with this call and continues until the run is stopped. 

# The overrides pin named entities to a treatment so you can exercise the 

# application path. Overridden entities are deliberately left out of the 

# assignment log, so this window cannot validate that pipeline. 

aws appconfig start-experiment-run \ 

  --application-identifier "StoreFront" \ 

  --experiment-definition-identifier "add-to-cart-redesign" \ 

  --exposure-percentage 0 \ 

  --treatment-overrides '[{"TreatmentKey": "__t1__", 

                            "EntityIds": ["qa-jane", "qa-raj"]}, 

                           {"TreatmentKey": "__control__", 

                            "EntityIds": ["qa-sam"]}]' 


Define rollback triggers with Amazon CloudWatch alarms. Before you start a run, decide which metrics indicate unacceptable behavior and create Amazon CloudWatch alarms to watch them. Monitor those alarms throughout the run. If an alarm fires:

  • Evaluate the impact and scope of the regression.
  • Stop the experiment run — this ends audience exposure immediately and returns users to the currently deployed feature flag configuration.

Note that after you increase exposure, it cannot be decreased within the same run. This is intentional to prevent data corruption. To reduce exposure, stop the run and start a new one at a lower percentage.

# Example: alarm on elevated 5xx error rate to watch during the experiment. 

# The dimension is not optional: without it the alarm watches a metric that 

# never receives data, so it sits in INSUFFICIENT_DATA instead of firing. 

aws cloudwatch put-metric-alarm \ 

  --alarm-name "exp-add-to-cart-5xx" \ 

  --namespace "AWS/ApplicationELB" \ 

  --metric-name "HTTPCode_Target_5XX_Count" \ 

  --statistic Sum \ 

  --period 60 \ 

  --evaluation-periods 3 \ 

  --threshold 50 \ 

  --comparison-operator GreaterThanThreshold \ 

  --dimensions Name=LoadBalancer,Value=app/storefront-alb/50dc6c495c0c9188 \ 

  --treat-missing-data notBreaching 

A note on automatic rollback. AWS AppConfig environment monitors (alarms associated with an AppConfig environment) automatically roll back an unhealthy configuration deployment. They are scoped to deployments, not experiment runs:

  • While a run is active, AWS AppConfig manages the flag value for assigned entities. Ending exposure requires an explicit stop-experiment-run call.
  • Keep the monitors in place — you still deploy configurations during and after a run (promoting the winner is a deployment).
  • Treat the alarm-and-stop-the-run pattern above as the guardrail for the experiment itself.

Choose guardrail metrics by experiment type. The right alarm depends on what you’re testing:

  • Frontend/UI: page load time, client-side error rate, rendering failures, 5xx rate. A conversion lift means nothing if the page is throwing errors.
  • Backend: p99 latency, throughput, error rate, and resource-specific signals (for the cache example, cache hit ratio and database load). A treatment can look neutral on business metrics while degrading system health.

Operational hygiene. Follow these rules to keep your results valid:

  • Do not change treatment behavior mid-run — stop, modify, and start a new run instead, or you invalidate the data.
  • Avoid shipping unrelated changes or overlapping experiments on the same audience while a run is active.
  • Monitor operational metrics alongside your experiment metrics — a positive result on the headline metric can still hide a latency or error regression.

Analyzing Experiment Results

AWS AppConfig provides aggregate real-time metrics — exposure levels, treatment allocation, traffic distribution — but it doesn’t compute your results. Your metric definitions and raw data stay in your warehouse (Amazon S3 + Amazon Athena, Amazon Redshift, Snowflake, Databricks, or other) where you control exactly how success is measured.

The core principle: post-exposure attribution. Only count a user’s outcomes after the moment they were assigned to their treatment. Events before assignment don’t attribute to the experiment and bias your results. Concretely, you join your metric events to the Agent’s assignment records on entity ID, and keep only metric events whose timestamp is at or after that entity’s assignment timestamp.

Assuming the Agent’s assignment records and your metric events have landed in Amazon S3 and are queryable through Amazon Athena:

WITH assignments AS ( 

    SELECT 

        entityid                                AS entity_id, 

        treatmentkey                            AS treatment, 

        MIN(from_iso8601_timestamp(timestamp))  AS assigned_at 

    FROM treatment_assignments   -- AWS AppConfig Agent records from STDERR 

    WHERE type = 'AWS.AppConfig.TreatmentAssignment' 

      AND experimentdefinitionid = 'uioedbc' 

      AND experimentrunnumber = '5' 

    GROUP BY entityid, treatmentkey 

), 

attributed_conversions AS ( 

    SELECT 

        a.treatment, 

        a.entity_id, 

        COUNT(m.entity_id) AS conversions 

    FROM assignments a 

    LEFT JOIN experiment_events m          -- your existing outcomes table 

        ON  m.entity_id = a.entity_id      -- or m.customer_id, whichever column it already has 

        AND m.event_type = 'conversion' 

        -- post-exposure attribution: outcomes only count after assignment 

        AND from_iso8601_timestamp(m.timestamp) >= a.assigned_at 

    GROUP BY a.treatment, a.entity_id 

) 

SELECT 

    treatment, 

    COUNT(DISTINCT entity_id)                         AS assigned_users, 

    SUM(CASE WHEN conversions > 0 THEN 1 ELSE 0 END)  AS converters, 

    ROUND( 

        SUM(CASE WHEN conversions > 0 THEN 1 ELSE 0 END) * 100.0 

        / COUNT(DISTINCT entity_id), 2 

    )                                                 AS conversion_rate_pct 

FROM attributed_conversions 

GROUP BY treatment 

ORDER BY conversion_rate_pct DESC; 

This returns assigned users, converters, and conversion rate per treatment so you can compare each treatment against the control.

The only requirement on your outcomes data is that it carries the same identifier you passed as Entity-Id and a timestamp. Whatever table structure, column names, or warehouse you already use works — the join is on that shared identifier with a timestamp filter.

Adapting the query for other metrics. The assignments CTE and the post-exposure join are reusable; only the metric aggregation changes:

  • Backend/cache experiments: aggregate AVG(db_query_count), cache hit ratio, or approx_percentile(latency_ms, 0.99) per treatment to confirm the longer TTL cut load without hurting p99.
  • Continuous metrics generally: replace the converter count with AVG(...), SUM(...), or approx_percentile(...) over the attributed rows.

Before you declare a winner, check three things. First, confirm each treatment reached the sample size you set in your launch criteria. Second, confirm the split matches the configured weights; a 50/50 experiment that lands at 46/54 points to an assignment or logging bug, not a result. Third, run a significance test in your statistics tooling, such as a two-proportion z-test for conversion rate. Act on the result only when all three checks pass.

Stopping an experiment and promoting a winner

Stop an experiment run when you have a clear result, when something goes wrong, or when priorities shift. Stopping ends exposure immediately. AWS AppConfig stops managing the flag and your application serves whatever configuration is currently deployed to the environment.

Promoting the winner without a gap. The order matters. If you stop first, users briefly revert to the pre-experiment default while you redeploy. To avoid that:

  • While the experiment is still running, update the feature flag to match the winning treatment and deploy it. Assigned entities see no change — AWS AppConfig is still serving them their treatment.
  • Stop the experiment. AppConfig releases the flag, and your application picks up the configuration you just deployed: the winner, at 100%, with no gap.

Mind what you change in step 1. Add the winning values as a variant gated by the same audience rule the experiment uses, and nobody sees a change until you stop the run. Change the flag’s default value instead and everyone outside the experiment’s audience picks up the winning value the moment the deployment lands — choose this when you want a full release.

Cost considerations and cleaning up

You pay for experiment-run hours. Billing starts when you call start-experiment-run until you stop the run. Defining experiments and treatments is free.

What drives your bill:

  • Run duration. Stop the run once you have enough data to make a decision.
  • Concurrent runs. Each active run bills independently. Three simultaneous experiments means three times the hourly rate.
  • Your data pipeline. AWS AppConfig doesn’t charge for the assignment records the Agent emits; the pipeline that carries them does. CloudWatch Logs, Amazon Data Firehose, Amazon S3, Athena, and your guardrail alarms each bill at their normal rates — see each service’s pricing page, and AWS Systems Manager Pricing for experiment runs.

To keep costs down, estimate sample size upfront so you know roughly how long a run needs to last, and validate what you can in the 0% window before you ramp. The assignment-log pipeline is the exception: it produces records — and bills — only once real traffic is being assigned.

See AWS AppConfig experimentation pricing details here.

Clean up what you created. The run-hour charge stops only when you stop the run, and the assignment pipeline keeps billing for as long as it stays in place. When you have finished with the examples in this post, remove what you created in this order:

  • Stop any running experiment run. Exposure ends immediately and the run-hour charge stops. If you are promoting a winner, deploy the winning flag value first, as described above.
  • Delete the experiment definitions for both examples. ARCHIVE hides a definition but keeps its run history; DESTROY removes the definition and the history permanently.
  • Take down the assignment pipeline and the alarms: the Amazon CloudWatch Logs subscription filter, the Amazon Data Firehose delivery stream, and the guardrail alarms. Then unset EXPERIMENT_ASSIGNMENT_LOG_DESTINATION on the Agent and redeploy so it stops writing assignment records.
  • Decide what to do with the data. The assignment records in Amazon S3, the AWS Glue table over them, and your Athena query-results location all keep incurring storage charges. Delete them unless you want to keep the audit trail, along with the IAM roles and the log group you created only for this walkthrough.

Leave the feature flag and its configuration profile in place if your application still reads them — deleting the flag removes configuration your code depends on. Only the experiment definition has to go.

1. Stop the run – this ends exposure and the run-hour charge. 

aws appconfig stop-experiment-run \ 

  --application-identifier "StoreFront" \ 

  --experiment-definition-identifier "add-to-cart-redesign" \ 

  --run 5 

2. Delete both definitions. Use ARCHIVE instead of DESTROY to keep the run history for future reference

#    the run history for future reference. 

aws appconfig delete-experiment-definition \ 

  --application-identifier "StoreFront" \ 

  --experiment-definition-identifier "add-to-cart-redesign" \ 

  --delete-type DESTROY 


aws appconfig delete-experiment-definition \ 

  --application-identifier "Catalog" \ 

  --experiment-definition-identifier "cache-ttl-tuning" \ 

  --delete-type DESTROY 

3. Remove the assignment pipeline and the guardrail alarm. 

aws logs delete-subscription-filter \ 

  --log-group-name "/ecs/storefront" \ 

  --filter-name "appconfig-treatment-assignments" 


aws firehose delete-delivery-stream \ 

  --delivery-stream-name "experiment-assignments" 


aws cloudwatch delete-alarms --alarm-names "exp-add-to-cart-5xx" 

4. Optional and irreversible – drop the queryable copy of the assignment data. Substitute your own AWS Glue database name. 

aws glue delete-table \ 

  --database-name "experiments" \ 

  --name "treatment_assignments" 


aws s3 rm "s3://my-experiment-data/assignments/" --recursive 

Conclusion

In this post, we took a single idea — “we have a theory, but no production evidence” — and turned it into two concrete experiments using AWS AppConfig experimentation: a frontend button redesign and a backend cache-TTL change. In each case, we created an experiment definition and expressed the control and treatments as feature-flag variants. We delivered them through the Agent with gradual exposure and alarm guardrails, and analyzed results with post-exposure attribution in our own data warehouse.

Experimentation becomes part of the AWS AppConfig workflow you already use, and you keep ownership of your metrics, analysis, and data. You pay per experiment-run hour, so your cost grows with how much you test.

To go deeper, start with the AWS AppConfig experimentation documentation, review running and monitoring an experiment for guardrail best practices and try the hands-on workshop.

If you have questions or feedback, leave a comment on this post. To get started, open the AWS AppConfig console and create your first experiment definition.
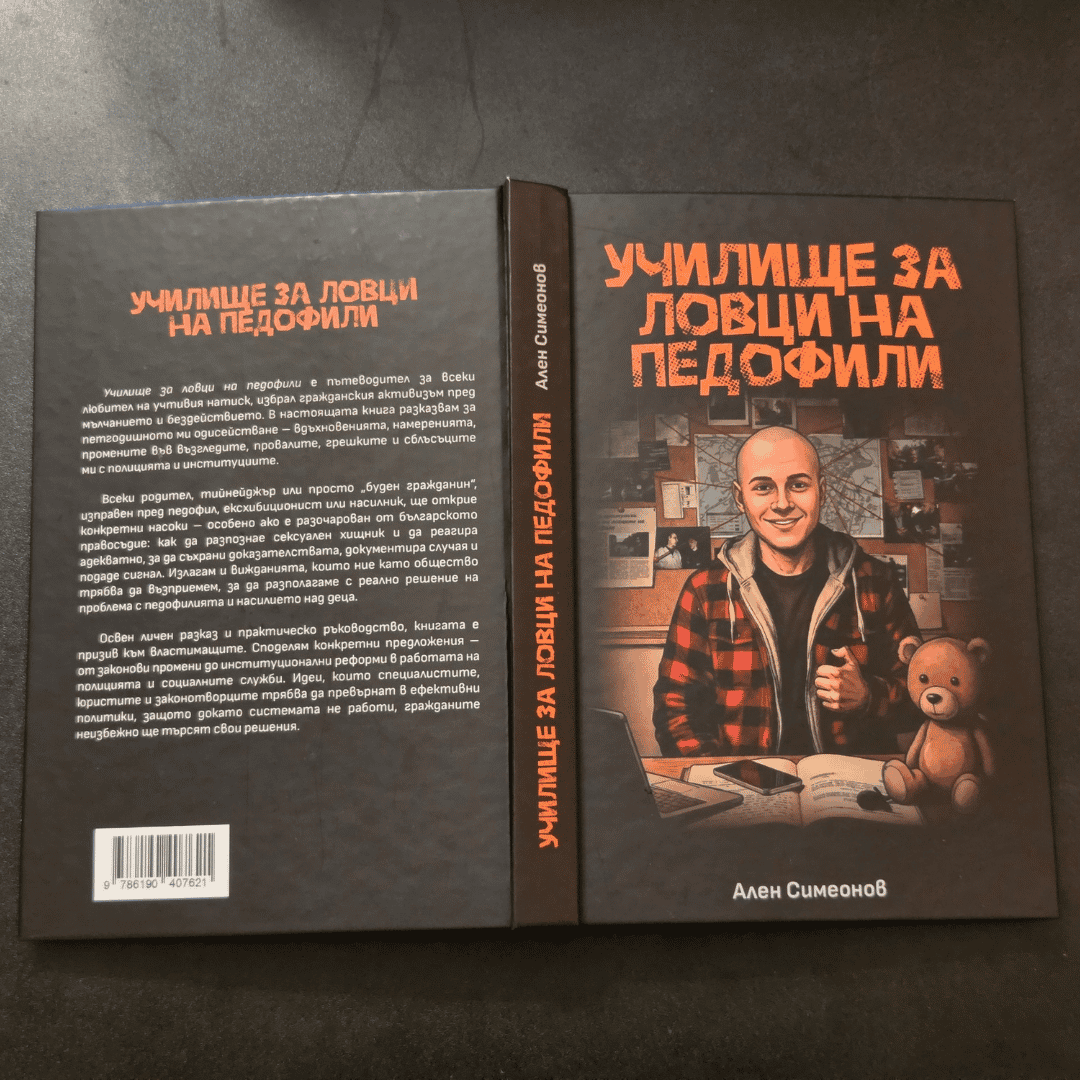
Running multi-day AZ evacuation drills with ARC Zonal Shift

Post Syndicated from Antoine Boucherie original https://aws.amazon.com/blogs/architecture/running-multi-day-az-evacuation-drills-with-arc-zonal-shift/

Running a multi-day Availability Zone evacuation drill with ARC Zonal Shift is an effective way to prove your application can withstand a sustained impairment. Multi-Availability Zone deployment is an architectural best practice for building resilient applications on AWS, but there is a gap between deploying multi-AZ and proving it works under sustained stress. Traditional disaster recovery (DR) tests validate the failover mechanism. A typical test shifts traffic, confirms targets respond, and rolls back within minutes. These short exercises don’t surface the issues that only appear over hours or days.

A multi-day AZ evacuation forces time-dependent behaviors to play out completely, exposing failure modes that brief tests miss:

  • Auto Scaling policies that aren’t tuned for sustained N-1 operation over a full day.
  • Deployment pipelines that don’t validate AZ health before placing new workloads.
  • Stale DNS or cached database endpoints.
  • Time-based routine operational processes tested against an N-1 architecture (certificate rotations, credential and secret rotations, maintenance windows, log rotation, backup automation, and cron jobs).
  • Long-lived database connections pinned to a specific AZ that are only used infrequently.
  • Recovery after a sustained multi-day shift, which is a different operational procedure than rolling back to a warm, nearly identical AZ within minutes.

By shifting all traffic away from a single AZ for 48–72 hours using Amazon Application Recovery Controller (ARC) Zonal Shift, you force your architecture to sustain full production load on N-1 zones. This proves capacity sufficiency, database stability, and client reconnection behavior, but most importantly, that your teams can operate normally for days on N-1 capacity.

This post shows you how to plan and run a multi-day AZ evacuation drill across Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), Amazon Relational Database Service (Amazon RDS) for PostgreSQL, and Amazon Aurora PostgreSQL, with step-by-step CLI commands, a prerequisites section, observability metrics, and restore procedures.

Why financial services institutions are doing this already

Financial services organizations face unique regulatory pressure to demonstrate, not just document, their disaster recovery capabilities. Across the world, there is an increasing focus on building and demonstrating operational resilience within regulated entities. This is shifting the mindset from “show us your runbook” to “show us the evidence”. This uplift in control environments is driving financial services companies to conduct live DR testing under realistic conditions and produce auditable proof of recovery within defined timeframes. Some insurers and banks are now running periodic AZ evacuation drills as part of their operational resilience programs, shifting from “we have multi-AZ” to “we have proven multi-AZ”. Using ARC Zonal Shift, you can shift traffic at the infrastructure layer without changing application code. It works natively across Application Load Balancer, Network Load Balancer, Amazon Elastic Compute Cloud (Amazon EC2) Auto Scaling groups, and Amazon EKS clusters.

Solution overview

In this walkthrough, we demonstrate how to evacuate an Availability Zone for a multi-tier digital platform running on AWS.

We deliberately include both ECS and EKS, and two database engines, to show the evacuation procedure for each major service type readers are likely to run. The architecture is illustrative only.

The following table outlines the architecture:

Layer Components Multi-AZ Configuration
Traffic ingress Application Load Balancer (ALB) fronting ECS Deployed across 3 AZs, cross-zone load balancing activated
Compute (containers) Amazon ECS (Fargate) Stateless tasks distributed across 3 AZ subnets
Traffic ingress Network Load Balancer (NLB) fronting EKS Deployed across 3 AZs, cross-zone load balancing activated
Compute (Kubernetes) Amazon EKS or EKS Auto Mode Stateless services with topology spread constraints across 3 AZs
Database Amazon RDS for PostgreSQL Multi-AZ: primary in AZ A, standby in AZ B
Database Amazon Aurora PostgreSQL Writer in AZ A, reader in AZ B. Storage replicated across all 3 AZs

Note that the Aurora storage layer differs from standard RDS Multi-AZ. Aurora synchronously replicates data to six storage nodes across Availability Zones independently of compute instances, so only the writer or reader instance needs to be failed over as the storage remains fully available throughout the drill.

In this walkthrough, we evacuate AZ A, the zone hosting the RDS primary and Aurora writer.

Multi-tier architecture spanning three Availability Zones: an Application Load Balancer fronting Amazon ECS and a Network Load Balancer fronting Amazon EKS, with Amazon RDS for PostgreSQL and Amazon Aurora PostgreSQL databases, before evacuating AZ A.

How ARC Zonal Shift works

When you initiate a zonal shift, ARC takes two coordinated actions for Amazon Route 53 and Elastic Load Balancers:

  1. DNS removal: The load balancer’s IP address in the affected AZ is removed from DNS. New client queries don’t resolve to that endpoint.
  2. Cross-zone traffic blocking: Load balancer nodes in the remaining AZs stop routing requests to targets in the shifted AZ, even when cross-zone load balancing is enabled.

For Amazon EKS clusters with zonal shift enabled, ARC goes further. It performs the following actions:

  • Cordons all nodes in the impacted AZ, preventing new pod scheduling.
  • Removes pod endpoints in the impacted AZ from EndpointSlice resources, redirecting east-west service-to-service traffic to healthy AZs.
  • Suspends AZ rebalancing for managed node groups and updates ASGs to launch instances only in healthy AZs.
  • Preserves nodes and pods in the shifted AZ (they are not terminated), keeping full capacity available for when the shift ends.

Combined with service-specific procedures for ECS task redistribution and database failover, this creates a complete AZ evacuation across all three traffic dimensions: north-south ingress, east-west service communication, and outbound database connections.

ARC Zonal Shift is a data plane operation by design. Because it works independently of the AWS control plane, it remains available even during an AZ impairment. The other steps in this walkthrough (ECS service updates, manual RDS failovers, manual Aurora failovers, subnet group modifications) are control plane operations. For a planned drill, this distinction has no practical impact because the control plane is healthy. During a real AZ impairment, prioritize the data plane action (start the zonal shift first to stop traffic immediately) and perform control plane operations only after traffic has already been shifted.

Prerequisites

Configure these prerequisites well in advance of your first shift. These are foundational settings that verify that your architecture is shift-ready at all times. For this walkthrough, you should have the following:

  • An AWS account
  • A multi-tier application deployed across 3 Availability Zones with ALB/NLB, ECS or EKS workloads, and RDS or Aurora databases.
  • IAM permissions to manage ARC Zonal Shift, ECS, EKS, and RDS resources.
  • AWS Command Line Interface (AWS CLI) v2 installed and configured.
  • Familiarity with ARC Zonal Shift concepts.
  • Amazon CloudWatch dashboards with per-AZ metric breakdowns (fault rate, latency, and target health).
  • Auto Scaling policies validated for sustained N-1 AZ operation.

Specifically for Elastic Load Balancing (ELB):

  • ALB/NLB deregistration delay set to 60 seconds, which allows existing connections to drain quickly after a shift instead of the default 300 seconds.
  • target_group_health.dns_failover.minimum_healthy_targets.count configured on each target group.

Specifically, for EKS:

  • kubectl installed and configured for your EKS cluster.
  • Turn on Topology Aware Routing on EKS services (or configure Istio locality-aware load balancing).
  • Zonal shift activated on your EKS cluster (one-time setup).

Specifically, for ECS:

  • ECS stopTimeout set to 55 seconds in task definitions, slightly below the ALB deregistration delay so tasks finish in-flight requests before being force-stopped, avoiding 502 errors during the drain window.

Specifically, for RDS:

  • Verify that your RDS primary and standby are provisioned in different Availability Zones.

What changes for a multi-day shift

The mechanics of starting a zonal shift are the same whether you run it for 1 hour or 72 hours. What changes is the operational surface area:

  • Expiry management: Zonal shifts have a maximum duration. You must monitor and extend them before they expire, or traffic returns to the shifted AZ unexpectedly.
  • Scaling drift: Over days, Auto Scaling events in healthy AZs may create capacity imbalances. Monitor and cap scaling so recovery doesn’t overload the returning AZ.
  • Connection pool cycling: After 24+ hours, most client connections will have recycled. This validates DNS TTL compliance across your entire client fleet, something a 1-hour test won’t fully exercise.
  • Operational confidence: Teams will learn to deploy, patch, and troubleshoot in a reduced AZ environment. A multi-day drill forces this to happen naturally rather than in a controlled window.
  • Safe recovery: After days at N-1 capacity, restoring the shifted AZ requires careful ordering. Verify health, scale back gradually, and reintroduce traffic incrementally rather than all at once.

Solution details

Each section below walks through the zonal shift procedure for one layer of the architecture, starting with the compute tier and finishing at the database layer.

Amazon ECS — Zonal Shift with task redistribution

For ECS services behind an ALB, initiating a zonal shift at the load balancer layer stops new traffic from reaching targets in the evacuated AZ. Existing ECS tasks in that AZ remain running but stop receiving requests. To perform a complete evacuation, follow these steps:

Step 0. Before starting, verify ARC Zonal Shift is enabled on the load balancer (disabled by default)

aws elbv2 modify-load-balancer-attributes \
    --load-balancer-arn $ALB_ARN \
    --attributes Key=zonal_shift.config.enabled,Value=true

Step 1. Initiate the zonal shift on the load balancer.

aws arc-zonal-shift start-zonal-shift \
    --resource-identifier $ALB_ARN \
    --away-from $AZ_ID_TO_EVACUATE \
    --expires-in "72h" \
    --comment "Multi-day AZ evacuation drill"

Zonal shifts expire after the duration set in --expires-in. If the shift expires before you cancel it, traffic automatically returns to the shifted AZ. For a multi-day drill, monitor the remaining time and extend before expiry using:

aws arc-zonal-shift update-zonal-shift \
    --zonal-shift-id $SHIFT_ID \
    --resource-identifier $RESOURCE_ARN \
    --expires-in "24h" \
    --comment "Extending drill"

When cross-zone load balancing is enabled (the default for ALB), the shift instructs load balancer nodes in healthy AZs not to route requests to targets in the impaired AZ. Targets are fully isolated regardless of your cross-zone configuration.

Step 2. Restrict new task placement to healthy AZs.

Update the ECS service’s network configuration to exclude subnets in the evacuated AZ. This prevents new tasks from launching in the shifted zone:

aws ecs update-service \
    --cluster $CLUSTER_NAME \
    --service $SERVICE_NAME \
    --network-configuration "awsvpcConfiguration={subnets=[$AZB_SUBNET,$AZC_SUBNET],securityGroups=[$SG_ID],assignPublicIp=DISABLED}"

Step 3. If needed, scale to verify N-1 AZ capacity.

aws ecs update-service \
    --cluster $CLUSTER_NAME \
    --service $SERVICE_NAME \
    --desired-count $N_MINUS_1_COUNT

Note: updating the ECS service network configuration and count that you want are control plane operations. Perform these changes before the drill starts, not during a real AZ impairment when control plane availability may be degraded.

We recommend that you pre-scale your services to handle the loss of an AZ’s worth of capacity before the drill. Your architecture should tolerate AZ loss without needing to scale reactively. See static stability in the Amazon Builders’ library.

In a 3 AZ environment, pre-scaling for N-1 capacity means running approximately 50% more compute than your baseline peak requires. If the cost isn’t justifiable for all workloads, consider scheduled scaling policies that increase capacity during planned drill windows, Auto Scaling with aggressive scale-out thresholds, or load shedding mechanisms. Keep in mind that during an unplanned impairment, you won’t have time to scale reactively. Workloads that aren’t pre-scaled will operate in a degraded state until scaling catches up, which can take minutes under load.

Step 4. Monitor task distribution.

aws ecs describe-tasks \
    --cluster $CLUSTER_NAME \
    --tasks $(aws ecs list-tasks --cluster $CLUSTER_NAME --service-name $SERVICE_NAME --query 'taskArns' --output text) \
    --query 'tasks[].[taskArn,availabilityZone]' --output table

Restore: Revert the network configuration to include all three AZ subnets, then cancel the zonal shift. Tasks will gradually rebalance across all AZs during subsequent deployments.

Important: zonal shift won’t work for single-AZ target groups as the ALB will refuse the shift if healthy targets only exist in one Availability Zone. Verify each target group has targets registered in at least two AZs before proceeding. For more details, refer to Application Load Balancers in the ARC documentation.

Amazon EKS — Zonal Shift with EndpointSlice isolation

Amazon EKS natively supports ARC zonal shift. When you turn on this capability and trigger a shift, ARC handles both the infrastructure and Kubernetes networking layers automatically.

What ARC does when you shift an EKS cluster:

  • Nodes in the impacted AZ are cordoned (no new pod scheduling).
  • The built-in Kubernetes EndpointSlice controller removes pod endpoints in the impacted AZ, so east-west service traffic is automatically redirected to pods in healthy AZs.
  • For managed node groups, AZ rebalancing is suspended and ASGs are updated to only launch in healthy AZs.
  • Nodes and pods in the shifted AZ are not terminated, ensuring full capacity is immediately available when the shift ends.

Step 1. Activate zonal shift for your EKS cluster (one-time setup):

aws eks update-cluster-config \
    --name $CLUSTER_NAME \
    --zonal-shift-config enabled=true

Step 2. Start the zonal shift on both the load balancer and EKS cluster:

# Shift north-south traffic at the load balancer
aws arc-zonal-shift start-zonal-shift \
    --resource-identifier $NLB_ARN \
    --away-from $AZ_ID_TO_EVACUATE \
    --expires-in "72h" \
    --comment "Multi-day AZ evacuation drill - north-south traffic"

# Shift east-west traffic within the EKS cluster
aws arc-zonal-shift start-zonal-shift \
    --resource-identifier $EKS_CLUSTER_ARN \
    --away-from $AZ_ID_TO_EVACUATE \
    --expires-in "72h" \
    --comment "Multi-day AZ evacuation drill - east-west traffic"

Step 3. Verify EndpointSlice update: confirm pods in the shifted AZ are no longer receiving traffic:

# Endpoints should only show AZ B/AZ C
kubectl get endpointslices -l kubernetes.io/service-name=$SERVICE_NAME -o yaml | \
    grep -A2 "zone:"

Step 4. Verify node and pod status:

# Nodes in evacuated AZ should show SchedulingDisabled
kubectl get nodes -l topology.kubernetes.io/zone=$AZ_NAME_TO_EVACUATE

# Confirm traffic distribution across healthy AZs
kubectl get pods -o wide -l app=$APP_LABEL

Verify your pods use topologySpreadConstraints with maxSkew: 1 on topology.kubernetes.io/zone and are pre-scaled to handle N-1 AZ load. The zonal shift doesn’t evict pods or trigger autoscaling by itself.

Note that ARC zonal shift doesn’t control outbound connections from pods to external dependencies like Amazon RDS. If your pods connect to AZ-specific database endpoints, consider using Istio with locality-aware routing. For implementation details, refer to End-to-end recovery from AZ impairments in EKS using Zonal Shift and Istio.

For Aurora, the cluster endpoint automatically routes to the current writer regardless of AZ, so no Istio configuration is needed for writer traffic. However, if you use AZ-specific reader instance endpoints, configure Istio ServiceEntry resources for each endpoint and apply a DestinationRule with localityLbSetting to prefer healthy AZs. This directs outbound database traffic to follow the same shift pattern as your north-south and east-west traffic.

Restore: Cancel both zonal shifts. ARC automatically uncordons nodes, adds pod endpoints back to EndpointSlices, and restores AZ rebalancing. Traffic returns to all three AZs with full capacity already in place.

aws arc-zonal-shift cancel-zonal-shift \
    --zonal-shift-id $EKS_SHIFT_ID \
    --resource-identifier $EKS_CLUSTER_ARN

aws arc-zonal-shift cancel-zonal-shift \
    --zonal-shift-id $NLB_SHIFT_ID \
    --resource-identifier $NLB_ARN

Amazon RDS for PostgreSQL — multi-AZ failover

Regarding Amazon RDS for PostgreSQL in a Multi-AZ deployment, if the primary instance resides in the AZ being evacuated, you must trigger a failover to the synchronous standby. RDS handles this through a reboot with failover.

Prerequisite: verify your RDS primary and standby are provisioned in different Availability Zones. If both are in the same zone, the following steps wouldn’t evacuate the zone as intended.

Step 1. Check current primary location:

aws rds describe-db-instances \
    --db-instance-identifier $RDS_INSTANCE \
    --query 'DBInstances[0].[DBInstanceIdentifier,AvailabilityZone,MultiAZ,SecondaryAvailabilityZone]' \
    --output table

Step 2. If the primary is in the evacuated AZ, manually force failover:

aws rds reboot-db-instance \
    --db-instance-identifier $RDS_INSTANCE \
    --force-failover

Step 3. Wait for availability and verify the new primary AZ:

aws rds wait db-instance-available \
    --db-instance-identifier $RDS_INSTANCE

aws rds describe-db-instances \
    --db-instance-identifier $RDS_INSTANCE \
    --query 'DBInstances[0].AvailabilityZone'

After failover, RDS recreates the standby in the evacuated AZ automatically. This is acceptable for a sustained drill as the standby receives no client traffic. Monitor ReplicaLag to confirm replication health.

Step 4. (Optional) Remove the standby from the evacuated AZ.

If you want zero RDS presence in the evacuated Availability Zone, you can relocate the standby by modifying the DB subnet group:

  1. Create a manual snapshot as a safety net.
  2. Disable Multi-AZ on the instance.
  3. Modify the DB subnet group to include only healthy AZ subnets, removing the evacuated AZ subnet.
  4. Re-enable Multi-AZ so the new standby is created in one of the remaining healthy AZs.

This approach works the same way for Amazon RDS for PostgreSQL as it does for any RDS engine using Multi-AZ deployments. Note that RDS Multi-AZ modifications (disabling/re-enabling Multi-AZ, subnet group changes) can take several minutes to complete. Plan for this during the drill window.

Amazon Aurora PostgreSQL — writer failover & reader management

Aurora provides more control over AZ placement than standard RDS Multi-AZ. You can explicitly choose which reader to promote and manage reader placement across AZs using failover priority tiers.

Step 1. Identify the cluster topology:

aws rds describe-db-clusters \
    --db-cluster-identifier $CLUSTER_ID \
    --query 'DBClusters[0].DBClusterMembers[].{Instance:DBInstanceIdentifier,IsWriter:IsClusterWriter}'

aws rds describe-db-instances \
    --filters Name=db-cluster-id,Values=$CLUSTER_ID \
    --query 'DBInstances[].[DBInstanceIdentifier,AvailabilityZone,DBInstanceStatus]' \
    --output table

Step 2. If the writer is in the evacuated AZ, failover to a reader in a healthy AZ:

aws rds failover-db-cluster \
    --db-cluster-identifier $CLUSTER_ID \
    --target-db-instance-identifier $READER_IN_HEALTHY_AZ

Step 3. Wait for the cluster to stabilize:

aws rds wait db-cluster-available \
    --db-cluster-identifier $CLUSTER_ID

If your Aurora cluster has no pre-existing reader in a healthy AZ, writer promotion requires creating a new instance, which typically takes less than 10 minutes. Pre-provisioning a reader in a separate AZ reduces failover time, often to less than 30 seconds.

Step 4. (Optional) Remove the reader in the evacuated AZ and create one in a healthy AZ.

For a full AZ evacuation where you want zero database presence in the shifted zone:

# Delete the reader instance in the evacuated AZ
aws rds delete-db-instance \
    --db-instance-identifier $INSTANCE_IN_EVACUATED_AZ \
    --skip-final-snapshot

# Create a new reader in a healthy AZ
aws rds create-db-instance \
    --db-instance-identifier ${CLUSTER_ID}-reader-${TARGET_AZ} \
    --db-cluster-identifier $CLUSTER_ID \
    --db-instance-class $INSTANCE_CLASS \
    --engine aurora-postgresql \
    --availability-zone $TARGET_AZ

Step 5. Monitor replication and performance throughout the drill:

aws cloudwatch get-metric-statistics \
    --namespace AWS/RDS \
    --metric-name AuroraReplicaLag \
    --dimensions Name=DBInstanceIdentifier,Value=$READER_INSTANCE \
    --start-time $TIMESTAMP_5MIN_AGO \
    --end-time $TIMESTAMP \
    --period 60 --statistics Average

Monitoring the drill with CloudWatch

A multi-day drill is only as valuable as the evidence it produces. Unlike a brief failover test where you visually confirm targets respond, a 48–72-hour evacuation requires continuous, automated observation, capturing capacity trends, replication health, and latency shifts that only surface under sustained N-1 AZ load.

Before starting the drill, verify you have CloudWatch dashboards with per-AZ metric breakdowns for each layer of your architecture. During the drill, these metrics serve two purposes: real-time operational awareness and post-drill evidence for stakeholders.

Key metrics by layer

The following metrics give you real-time visibility into each layer of the architecture during the drill.

Application Load Balancer / Network Load Balancer

Metric Dimension What to watch
HealthyHostCount Per target group, per AZ Should drop to 0 in evacuated AZ. Stable in healthy AZs
UnHealthyHostCount Per target group, per AZ Targets in evacuated AZ may show unhealthy (expected)
RequestCount Per AZ Zero traffic in shifted AZ. Even distribution in remaining AZs
TargetResponseTime Per AZ Watch for latency increases in healthy AZs under concentrated load
HTTPCode_Target_5XX_Count Per target group Sustained increase signals capacity pressure

Amazon ECS

Metric Dimension What to watch
CPUUtilization Per service Should not exceed 70–80% sustained (indicates capacity headroom)
MemoryUtilization Per service Memory pressure under concentrated load
RunningTaskCount Per service Confirms tasks running only in healthy AZs
DesiredTaskCount vs RunningTaskCount Per service Gap indicates placement failures (check subnet/capacity)

Amazon EKS (using Container Insights)

Metric Dimension What to watch
node_cpu_utilization Per node, filtered by AZ Nodes in healthy AZs absorbing shifted load
pod_cpu_utilization Per pod/namespace Hotspot detection under N-1 operation
node_status_condition Per node Nodes in evacuated AZ should show SchedulingDisabled
pod_number_of_container_restarts Per pod Restart loops may indicate resource pressure

Amazon RDS for PostgreSQL

Metric Dimension What to watch
CPUUtilization Per instance Primary under higher load post-failover
DatabaseConnections Per instance Connection spike after failover (watch for pool exhaustion)
ReadIOPS / WriteIOPS Per instance I/O patterns shift when primary moves AZs
ReplicaLag Per standby Should stabilize within seconds after failover
FreeableMemory Per instance Memory pressure under full client reconnection

Amazon Aurora PostgreSQL

Metric Dimension What to watch
AuroraReplicaLag Per reader instance Establish your cluster baseline during normal operation. Sustained increases from baseline indicate storage pressure. Aurora Replicas typically lag 100 ms or less
CommitLatency Per writer Increased commit latency indicates write contention
BufferCacheHitRatio Per instance Drop below 99% may indicate working set doesn’t fit in memory
DatabaseConnections Per instance Client reconnection behavior after writer promotion
VolumeBytesUsed Per cluster Aurora storage is AZ-independent (should be unaffected)

Export your per-AZ CloudWatch dashboards as snapshots before, during, and after the drill. Combine these with the ARC zonal shift event history (available through list-zonal-shifts) to create an auditable evidence package.

Cleaning up

After completing the drill, restore services carefully. The order matters, especially if Auto Scaling has increased capacity in healthy AZs:

  1. Verify the evacuated AZ is healthy: confirm targets are registered, pods are running, and database instances are available.
  2. Cancel the EKS cluster zonal shift first (east-west traffic resumes). Monitor for errors as internal traffic rebalances.
  3. Cancel the load balancer zonal shift (north-south traffic resumes). Traffic returns gradually as DNS propagates.
  4. If Auto Scaling added capacity in the remaining AZs, scale back gradually over 15 to 30 minutes. Don’t remove capacity before traffic has redistributed evenly.
  5. If cross-zone load balancing is disabled, verify target_group_health.dns_failover.minimum_healthy_targets.count is configured. This allows Route 53 to only route traffic to an AZ once it has enough healthy targets registered, preventing the restored zone from receiving traffic before it’s ready to handle it.
  6. Monitor per-AZ metrics for 30 minutes after restoring to confirm even distribution and no error spikes.

No additional AWS resources are created by ARC Zonal Shift that incur ongoing charges. The zonal shift itself is available at no additional cost.

Conclusion

In this post, you learned how to run a sustained AZ evacuation drill using ARC Zonal Shift across Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), Amazon RDS for PostgreSQL, and Amazon Aurora. By operating on N-1 Availability Zones for 48–72 hours, rather than a brief failover test, you produce evidence that your multi-AZ architecture delivers genuine, sustained resilience. This is particularly valuable for financial services organizations facing regulatory mandates that require demonstrated recovery capabilities.

To get started, use the prerequisites checklist and step-by-step procedures in this post. Begin in non-production, progress to production during low-traffic windows, and build toward sustained operation under shift. As confidence grows, activate zonal autoshift so AWS can shift traffic automatically when internal telemetry detects an impairment.

You can also use AWS Resilience Hub to assess your application’s resilience posture before and after the drill. It validates that your architecture meets your defined Recovery Time Objective (RTO) and Recovery Point Objective (RPO) targets.

Amazon Application Recovery Controller – Zonal Shift

Best practices for zonal shifts in ARC

Using cross-zone load balancing with zonal shift

New AWS Fault Injection Service recovery action for zonal autoshift

End-to-end recovery from AZ impairments in Amazon EKS using EKS Zonal Shift and Istio

Amazon EKS now supports Amazon Application Recovery Controller


About the authors

How MHK built a HIPAA-eligible agentic AI solution on Amazon Bedrock

Post Syndicated from Deepti Tirumala original https://aws.amazon.com/blogs/architecture/how-mhk-built-a-hipaa-eligible-agentic-ai-solution-on-amazon-bedrock/

Healthcare organizations face an increasingly complex challenge: processing vast volumes of medical documents, including clinical records, claims, prior authorizations, appeals, and pharmacy data, while maintaining strict HIPAA compliance and security standards. Traditional approaches require dedicated engineering teams to build individual AI systems for each use case, each needing its own compliance infrastructure, audit trails, and security controls. Agentic frameworks that can scale across use cases can reduce lengthy development cycles and high operational overhead.

MHK, a Hearst Health company ranked #1 in payer care management solutions in the 2024 Best in KLAS: Software & Services Report, faced this exact challenge. Their medical management solution serves health plans across multiple workflows (medical, pharmacy, grievance, and appeals), each requiring intelligent document processing and decision support. Building separate AI systems for each workflow was unsustainable as demand grew.

To solve this, they developed the SmartProminence AI Orchestrator, a HIPAA-eligible agentic workflow framework built on AWS that reduced manual medical review effort by 90%. New AI features that previously took 3+ months to deploy now ship in 2 weeks.

In this post, we walk through how MHK architected this solution using Amazon Bedrock, Amazon Elastic Container Service (Amazon ECS), and event-driven patterns to create a reusable, multi-tenant orchestrator for healthcare AI.

MHK uses Amazon Bedrock exclusively for foundation model inference. They built their own orchestration, retrieval, and validation layers because healthcare workflows require domain-specific controls: DAG-based multi-step execution, clinical document retrieval tied to case context, and HIPAA-specific validation logic that goes beyond general-purpose guardrails. This approach keeps Bedrock focused on scalable model access while MHK retains full control over workflow behavior and compliance enforcement.

Background

MHK provides healthcare cost management and compliance solutions to health plans across the United States. Their medical management system supports the full lifecycle of care decisions, from the moment a provider submits a request for service through final resolution. This includes prior authorization, claims adjudication, appeals processing, pharmacy benefit verification, and medical director reviews.

Each workflow involves analyzing unstructured medical documents such as clinical notes, lab results, imaging reports, and multi-page faxed records, against structured policy criteria. Before MHK’s SmartProminence AI Orchestrator, case managers spent 5 to 10 minutes manually processing each incoming document, while medical directors spent longer reviewing complex cases that required policy adherence determinations.

MHK needed to automate this research while maintaining healthcare’s audit trail and compliance requirements, and to do so across all product modules without building separate AI infrastructure for each one.

Business challenge

As MHK evaluated how to bring AI capabilities across their entire product suite, three core challenges emerged.

  • Fragmented AI infrastructure. Each AI-powered feature would require its own deployment pipeline, HIPAA compliance certification, security controls, and monitoring. Every new AI roadmap item meant a new cluster, a new compliance engagement, and a new operational burden. For a company serving multiple health plans across multiple modules, this approach could not scale.
  • Lengthy development cycles. Deploying a new AI workflow through traditional engineering took 3 to 6 months, not including requirements gathering. The engineering team could not keep pace with the product roadmap.
  • Manual effort at premium cost. Case managers, nurses, pharmacists, and medical directors spent hours per case manually searching through patient records. The cost was especially acute for medical directors (physicians) and pharmacists, whose hourly rates make even small-time savings translate into significant ROI.

Solution overview: SmartProminence AI Orchestrator

MHK built the SmartProminence AI Orchestrator, a multi-tenant, agentic workflow framework running entirely on AWS. Rather than building separate AI systems for each use case, MHK created a single orchestrator where various AI workflows can be deployed through configuration. Define your prompts, specify your input/output schemas, and register the agent. The solution handles everything else including HIPAA compliance, encryption, audit trails, scaling, and orchestration.

The solution is architected around a controller-agent pattern in which a Workflow Engine Controller resolves workflow dependencies and dispatches individual steps to LLM processing agents. The entire system is stateless, event-driven, and independently scalable.

The following diagram illustrates the high-level architecture of the solution.

Architecture of the MHK SmartProminence AI Orchestrator on AWS, showing the orchestration core, workflow controllers, and processing agents communicating through Amazon SQS queues

Figure 1: MHK SmartProminence AI Orchestrator architecture on AWS

At the core of the architecture, the Agent Orchestration Core serves as the central nervous system. Built on Spring Boot and running on AWS Fargate, it exposes a REST API that handles job submission, workflow management, LLM proxying, and token management. Critically, it is the only component that directly accesses the database: controllers and agents interact exclusively through the orchestration core’s API, enforcing strict data access boundaries.

Architecture overview

This section examines the key architectural patterns the orchestrator uses to process diverse healthcare workflows at scale.

Controller-agent pattern with Amazon Bedrock

MHK selected Amazon Bedrock for its multi-model access through a single API, letting them choose the best model per workflow step without separate integrations. As a managed AWS service, Bedrock inherits existing AWS Identity and Access Management (IAM), Amazon Virtual Private Cloud (Amazon VPC), and encryption controls, avoiding a new trust boundary. Built-in content filtering and invocation logging satisfy healthcare auditability requirements, and its model-agnostic architecture lets MHK adopt newer models without rearchitecting the solution.

The orchestrator enforces a strict separation between workflow orchestration and LLM processing. The Workflow Engine Controller determines what needs to happen and in what order, while LLM processing agents execute individual steps. This separation lets agent processing scale independently from workflow logic, and it makes the workflow the single source of truth while agents operate only on specific, actionable steps.

When a job arrives, the controller loads the version-pinned workflow definition, resolves step dependencies into a DAG using Kahn’s algorithm, and pre-creates step executions in a WAITING state. It uses conditional Spring Expression Language (SpEL) expressions to decide which steps to run versus skip, then dispatches agents layer by layer. Steps at the same depth run in parallel, and the controller polls for completion before advancing to the next depth.

Each agent runs a standardized pipeline: input binding (resolving expressions to gather prior step results), optional vision processing for scanned documents, prompt assembly with enriched context, LLM invocation to Amazon Bedrock (Claude), and post-processing for field extraction, type coercion, and structured output.

For parallel workloads within a single step, agents use Java virtual threads for each execution. This lets them process multiple items concurrently, such as extracting data from each page of a multi-page document simultaneously.

Event-driven orchestration with Amazon SQS

Communication between the orchestration core, controllers, and agents flows through Amazon Simple Queue Service (Amazon SQS) queues. To trigger a workflow, the orchestration core places a ControllerTaskMessage on the Controller Invoke Queue. To dispatch an individual step, it places an AgentTaskMessage on the Agent Invoke Queue. Each message is secured with a capability token scoped to only that operation’s data.

This design delivers four properties. Stateless processing means available instances can pick up pending messages. Independent scaling lets agents scale horizontally through ECS Fargate. Fault isolation keeps a failed task from blocking parallel steps, and dead letter queues capture failures. Decoupled deployment ships new agent versions without system-wide restarts.

The only blocking call in the pipeline is the LLM invocation to Amazon Bedrock. Everything else is asynchronous and event-driven, so the system can process hundreds of concurrent jobs without resource contention.

DAG-based parallel execution

The workflow engine uses depth-based parallel execution to maximize throughput. Consider a medical policy review workflow: at Depth 0, agents simultaneously extract patient demographics and pull claims history. At Depth 1, once both are complete, a policy lookup agent identifies the relevant criteria. At Depth 2, an evidence-gathering agent searches through the patient’s clinical history for documentation that satisfies each policy criterion. The controller only advances to the next depth when steps at the current depth have completed.

Conditional expressions can dynamically skip steps based on upstream results. For example, if the initial classification step determines that a case does not involve prescription drugs, the pharmacy verification step at the next depth is automatically skipped, saving both time and token costs. This conditional logic is evaluated by the controller using Spring Expression Language (SpEL) against the structured outputs of completed steps.

Dynamic agent registry

When MHK needs a new agent type, whether for a new medical management module or a new kind of analysis, the process is configuration-driven rather than engineering-driven.

A developer defines the agent configuration (prompt templates, input/output schemas, and model selection), then registers it through the orchestration core’s API. Terraform automatically provisions the supporting infrastructure: SQS queues, IAM roles, and ECS task definitions. The agent immediately becomes available for workflow step assignments, with no new compliance certification needed, since it runs within the already certified orchestrator.

This transformed MHK’s development velocity. The engineering team focuses on prompt design and workflow logic rather than infrastructure scaffolding.

Conversational memory and case association

The orchestrator maintains context across multiple workflow executions for the same patient case. Each execution returns a job ID that the upstream system associates with the case record. Over a case’s lifetime there may be three or more executions (initial intake, policy review, and appeal processing), each producing structured outputs that stay available for later executions.

Once a 30-page clinical record has been analyzed, its structured output is available for future queries on that case without re-running ingestion. When a medical director reviews an appeal weeks later, the patient’s history is already organized and searchable.

Prior context remains in Amazon Simple Storage Service (Amazon S3), encrypted with the client’s dedicated AWS Key Management Service (AWS KMS) key.

Responsible AI controls

MHK enforces safe LLM outputs through application-layer validation built into each agent’s processing pipeline. Every agent post-processes model responses against expected output schemas, cross-references extracted data with source documents to detect hallucinations, and rejects responses that fail confidence thresholds. Domain-specific checks verify that outputs reference only the patient’s own clinical records and match policy-specific medical criteria. LLM inputs and outputs are logged with full audit trails, which supports compliance review and reproducibility for every AI-assisted decision.

AWS services used

The following table summarizes the AWS services that compose the SmartProminence AI Orchestrator and the role each plays in the architecture.

Service Role in architecture
Amazon Bedrock Foundation model inference with IAM role-based authentication
Amazon ECS (Fargate) Containerized orchestration core, workflow controllers, and processing agents
Amazon SQS Event-driven inter-component communication with dead letter queues for fault tolerance
Amazon RDS (MySQL 8.4) Workflow definitions, execution state tracking, multi-AZ for high availability
Amazon S3 Job artifacts, document storage, immutable workflow configurations (KMS encrypted)
AWS KMS

Capability token signing and validation

Per-client encryption keys for multi-tenant data isolation

Amazon Cognito OAuth2/JWT authentication for API access and user identity
Amazon CloudWatch Logging, metrics, token usage tracking, and alerting (no PHI)
Elastic Load Balancing TLS 1.3-terminated application load balancer
Amazon VPC Network isolation with private subnets, VPC endpoints for service access

Security and compliance

Healthcare data demands the highest security standards, and MHK’s architecture implements defense-in-depth across every layer. The orchestrator processes protected health information (PHI) for multiple health plan clients simultaneously, making multi-tenant data isolation a foundational feature.

  • Per-client encryption. Every client has their own AWS KMS key. Documents stored in Amazon S3 are double-encrypted: S3 server-side encryption plus client-specific KMS encryption. Even if a job were somehow misrouted (which the token system helps prevent), the receiving agent could not decrypt another client’s data because it would not have access to that client’s KMS key. The database layer adds row-level encryption on top of Amazon Relational Database Service (Amazon RDS) storage-level encryption, providing defense-in-depth for data at rest.
  • Capability token model. A least-privilege token system limits what each component can access. A controller-scoped token can read workflow definitions and job data, dispatch agent tasks, and create step executions. An agent-scoped token can only read its step’s input, write its own result, call the LLM through the proxy, and upload artifacts. Tokens are generated per-dispatch through KMS, so even a compromised agent cannot reach data from other steps, workflows, or clients.
  • Network isolation. The database subnets have no internet access. AWS service communication (Amazon S3, Amazon SQS, AWS KMS, AWS Secrets Manager, Amazon CloudWatch, Amazon Elastic Container Registry (Amazon ECR)) flows through VPC endpoints, meaning no data ever traverses the public internet. Connections use TLS 1.3 for encryption in transit.
  • Compliance controls. LLM request and response bodies are not logged. Only token counts and content hashes are recorded. Workflow configurations are stored immutably in S3 for complete version history. Agents receive only the minimum context needed for their step, following the principle of data minimization.

Results and impact

The SmartProminence AI Orchestrator delivered measurable business outcomes across both MHK’s internal operations and their health plan clients.

90% reduction in manual review effort. For document intake workflows, processing time dropped from 5–10 minutes per document (manual) to under 1 minute (automated with human-in-the-loop verification). For complex medical director reviews, the system pre-gathers the relevant evidence and presents a structured summary, reducing the physician’s task from hours of document searching to a 30-second approval or denial decision.

85% faster AI feature deployment. New AI capabilities that previously required a full 3–6 month engineering release cycle now deploy in approximately 2 weeks. The engineering team defines workflow configuration and prompt logic without building custom infrastructure, compliance pipelines, or security controls for each feature.

Unified compliance posture. Instead of attesting each AI feature independently, MHK maintains a single orchestrator-level HIPAA and SOC 2 attestation that covers the agents. New agents inherit the orchestrator’s security controls automatically: per-client encryption, audit logging, token-based access, and data minimization.

Multi-tenant extensibility. Health plan clients can run AI workflows through the framework without building their own HIPAA-eligible infrastructure. Because the orchestrator is configuration-driven, MHK can onboard new use cases for existing clients or deploy entirely new health plan customers with minimal engineering effort.

Conclusion

The orchestrator’s controller-agent architecture provides a blueprint for organizations that need to scale AI capabilities across multiple use cases without multiplying their compliance burden. The key insight is that compliance infrastructure should be an orchestrator-level concern, not a per-feature concern, and that agentic orchestration patterns can be both powerful and auditable when designed with healthcare-grade security from the ground up.

Looking ahead, MHK is extending the orchestrator with conversational interfaces so case managers and medical directors can interactively query case data, using the same workflow memory and security infrastructure. The dynamic agent registry continues to grow as new medical management modules adopt AI-powered decision support. MHK is also exploring AWS Marketplace as a distribution channel to bring their HIPAA-eligible agentic framework to organizations beyond healthcare that require similar compliance thresholds.

Share your experience building HIPAA-eligible AI workflows in the comments or reach out if you’re exploring agentic architectures for regulated industries.

To learn more, get started with Amazon Bedrock and explore the Amazon Bedrock code samples to build your own agentic AI solutions on AWS.


About the authors

Amazon Aurora PostgreSQL now supports direct querying of Apache Iceberg and Parquet data in your data lake

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/amazon-aurora-postgresql-now-supports-direct-querying-of-apache-iceberg-and-parquet-data-in-your-data-lake/

Today, we’re announcing a new capability for Amazon Aurora PostgreSQL that you can use to directly query operational data together with data stored in your data lake in Apache Iceberg and Apache Parquet formats, using your existing PostgreSQL applications and tools. By eliminating the need to extract, transform, and load (ETL) structured data from data lakes into your operational database, you can reduce operational complexity and simplify application development. You can also use Aurora PostgreSQL to query data from data lakes managed in Iceberg REST Catalog (IRC)-compatible catalogs, giving you access to data across a breadth of analytics systems without moving or duplicating it. Whether you’re powering real-time dashboards, enriching transactions with historical context, or building AI agents that reason over both live and archived data, you can now do it all through a single, familiar interface.

Previously, if your application needed to combine recent transactional data in Aurora with historical records stored in Amazon S3, a common approach was to build reverse ETL pipelines that duplicated data, increased infrastructure costs, and required ongoing engineering effort to keep everything synchronized. This challenge only grows as you increasingly embed AI agents into your applications, where it is impractical to predict and pre-replicate every dataset an agent might need.

DuckLabs, the team that maintains the DuckDB project, recently joined Amazon, and this capability is an example of how the efficiency of DuckDB is being integrated into our services. DuckDB is now embedded directly within Aurora PostgreSQL, so you can query live operational data (including uncommitted writes) alongside your data lake in a single query. Query processing stays within Aurora, with no additional network hops and no ETL pipelines that duplicate data. You can query Apache Iceberg tables managed through the AWS Glue Data Catalog, as well as Parquet and Iceberg data stored in Amazon S3 and S3 Tables. You do all of this using familiar PostgreSQL syntax and your existing applications and tools.

We’re excited to bring the speed and simplicity of DuckDB directly into Aurora PostgreSQL, so you and your agents can query and combine operational and Iceberg data using the familiar PostgreSQL applications, tools, and endpoints already in use. By building this capability around DuckDB, future improvements to the open source engine can continue to bring performance and functionality gains to Aurora and other AWS services.

What is new

This capability is supported on two Aurora PostgreSQL major versions: 17 (starting with 17.11) and 18 (starting with 18.6). To use it, you create an Aurora PostgreSQL cluster, attach an IAM role with the AuroraAnalytics feature, and enable the aurora_analytics extension. The IAM role is what gives Aurora access to your data in Amazon S3 and the AWS Glue Data Catalog. You then create foreign tables that point to your Iceberg or Parquet data in the data lake, and query them using familiar PostgreSQL syntax. You can complete this setup through the Amazon RDS console, or with any PostgreSQL client such as psql. The process is well documented in the Aurora PostgreSQL documentation.

You can query data across external IRC-compatible catalogs through AWS Glue Data Catalog federation. You register the external catalog once with Glue, and then create foreign tables for the tables you want to query, the same way you would for any Glue-native table. A single query can then join data stored in Aurora with Iceberg tables registered across multiple catalogs, so applications get a unified view without moving data or replacing your existing catalog investments.

Aurora also applies optimizations such as predicate pushdown and column pruning so that only the relevant data is read. This keeps queries efficient even as the underlying data grows. Frequently accessed data is also cached in your Aurora instance, so subsequent queries against the same data return faster. You can inspect this behavior per query using aurora_analytics_stat_statements(), which reports metrics such as rows scanned, bytes read from Amazon S3, and cache hits.

To see how direct querying works, I connected to my Aurora PostgreSQL database using psql and created the extension:

CREATE EXTENSION aurora_analytics;

For my walkthrough, I set up a simple financial scenario. I have a recent_transactions table in Aurora with the last 7 days of customer transactions, and a Parquet file in Amazon S3 containing 5 years of historical transaction data. To make Aurora aware of the historical data, I created a foreign table pointing at the Parquet file in S3:

CREATE FOREIGN TABLE transaction_history ()
SERVER aurora_analytics_server
OPTIONS (
    location 's3://<my-bucket>/finance/transaction_history.parquet',
    format 'parquet'
);

Notice the empty parentheses in the CREATE FOREIGN TABLE statement. Aurora automatically reads the schema from the Parquet file metadata, so you do not need to define columns manually. For workloads with many tables, you can skip creating them one at a time: a single IMPORT FOREIGN SCHEMA statement bulk-creates foreign tables for every Iceberg or Parquet table in an AWS Glue Data Catalog database, inferring schemas automatically.

With both tables in place, I ran a single query that combines the recent operational data in Aurora with the historical data in S3:

SELECT merchant, category, amount, transaction_date, 'recent' AS source
FROM recent_transactions
WHERE customer_id = 'C-1001'
UNION ALL
SELECT merchant, category, amount, transaction_date, 'historical' AS source
FROM transaction_history
WHERE customer_id = 'C-1001'
  AND transaction_date >= CURRENT_DATE - INTERVAL '5 years'
ORDER BY transaction_date DESC
LIMIT 15;

The result shows both recent and historical transactions in a single result set. The 7 most recent rows come from Aurora, and the rest come directly from the Parquet file in S3. DuckDB handles the analytical scan of the Parquet data under the hood, while Aurora handles the operational data. That single query would have previously required a pipeline to move the historical data into the database first.

If a query pattern needs single-digit-millisecond latency, you can materialize data from the data lake into a native Aurora PostgreSQL table using familiar commands such as CREATE TABLE AS SELECT, INSERT INTO ... SELECT, or MERGE INTO. The materialized table lives in Aurora and is queried like any other PostgreSQL table, giving you a low-latency path for hot data without operating a separate ingestion pipeline. The read queries can run on any Aurora PostgreSQL instance in your cluster, whether the writer or a read replica, so you can offload analytical scans from your operational workload. The materialization commands write data into Aurora, so they run on the writer instance.

Get started today

Direct querying of Apache Iceberg and Parquet data from Amazon Aurora PostgreSQL is available today in all commercial AWS Regions and AWS GovCloud (US) Regions, at no additional charge. You pay only for the incremental Aurora compute the queries consume and Amazon S3 request costs for reading data lake files.

To learn more, visit the Amazon Aurora features page, read the Aurora PostgreSQL documentation, or try it in the Amazon RDS console. We welcome your feedback through AWS re:Post or through your usual AWS Support contacts.

— Esra

The collective thoughts of the interwebz