Security updates have been issued by AlmaLinux (pki-core), Debian (dlt-daemon and plasma-workspace), Fedora (emacs and kernel), Mageia (erofs-utils, libheif, libopenmpt, and wget), Red Hat (pki-core and python3), SUSE (frr), and Ubuntu (fontforge, sqlite3, and squid3).
Дебатът за мястото и ролята на Китай в глобалната политика става все по-динамичен в последните няколко години, което естествено налага необходимостта от по-дълбокото осмисляне на страната не просто като субект в системата на международните отношения, но и като отделно културно-политическо цяло, което съществено се различава от западната представа за модерна държавност.
В този смисъл съществуват множество концепции как следва да се възприема Пекин, и все пак най-общо те могат да бъдат разделени в две групи. Първата включва класическите школи в глобалната политика, като реализма, неолиберализма и функционализма. Те разглеждат Китай като велика сила, която – макар и със своя самобитна култура – не се различава от останалите велики сили по отношение на целите и стремежите във външната си политика.
Въпреки различията във визията си за структурата на международната система учени като Джоузеф Най, Алистър Джонсън, Джон Миършмайър, Франсис Фукуяма и Чарлс Купчан виждат в китайската външна политика една различна като ценности и инструменти система за вземане на решения, която всъщност е ориентирана към създаване на глобална архитектура за сигурност, доминирана от Пекин.
На другия полюс са набиращите сила азиатски концепции с автори като Йен Сюетун, Цин Яцин, Тан Шъпин и Джае-Хо Чунг, които виждат във възхода на Китай възможност за постигане на хармония в глобалната политика и мирно разрешаване на конфликтите в горещите точки на света.
Сблъсъкът между тези фракции в научната литература става все по-отчетлив, но ги обединява стремежът да обяснят Китай, който като идеи изглежда някак си далечен и неразбираем за западния човек, но като влияние е все по-близък и осезаем.
Как изглежда Китай след Гражданската война
Част от авторите, които се опитват да систематизират китайските външнополитически доктрини, често правят грешката да подхождат към тях едностранно, без да са запознати в дълбочина с идеите на бащите основатели на съвременен Китай. Това се дължи или на липсата на лингвистични познания, или на факта, че по-голямата част от теоретичните инструменти за анализ на политическите идеи са плод на западните автори, които задават основните направления в развитието на международните отношения след края на Втората световна война.
Или казано накратко, няма как да осмислим китайската политика днес, ако четем само Си Дзинпин или само Конфуций. Основен принцип в азиатските философии е взаимовръзката, която съществува между отделните философски категории и която коренно се отличава от системата, представена ни от Хегеловата диалектика. В този ред на мисли модерната китайска политика представлява своеобразна идеологическа сплав от идеите на постреволюционните китайски лидери и културното наследство на Конфуций, Лаодзъ и Мъндзъ.
Предобразите на модерната китайска концепция за външна политика следва да се търсят доста по-рано, в трудовете на Ли Даджао – възпитаник на елитния японски университет „Васеда“, и на неговия съмишленик Чън Дусиу. В първите дни след падането на династията Цин двамата създават социалистическата партия на Република Китай. В своите книги, които по-скоро носят духа на манифести, Ли и Чън обявяват, че Китайската република следва да изгради мощна и стабилна политическа система, която да е в състояние да се еманципира от западното влияние, провалило династията Цин, и да обедини азиатските народи.
Тези идеи вдъхновяват крайните националистически фракции в Китай, но срещат сериозна съпротива в лицето на комунистическия лагер, който обвинява Ли и Чън, че на практика приравняват китайският социализъм с японския империализъм. Разколът се задълбочава и води до края на Обединения фронт срещу японците и началото на Гражданската война между партията Гоминдан начело с Чан Кайшъ и Комунистическата партия на Мао Дзъдун.
След победата на Комунистическата партия и оттеглянето на Чан Кайшъ на остров Тайван, Мао Дзъдун създава Китайската народна република и в първите си речи осъжда идеите на ранните китайски социалисти като незрели и силно повлияни от японската окупация.
Първият етап, в който се формират модерните китайски външнополитически доктрини, е белязан от нов идеологически сблъсък, който се води между две комунистически фракции. Първата обединява героя от Гражданската война маршал Лин Бяо и един от най-близките съмишленици на Мао – Хуа Гуофън. Лин и Хуа настояват за изграждане на политическа система, която копира съветската и следва идеите на маоизма. За разлика от СССР обаче, крайните крила в Китай стигат по-далеч, като настояват, че маоизмът цели не просто победа над капиталистическата класа, а унищожаване на пазарните сили и замяната им с военизирана политическа система.
На този план се противопоставя „градското“ лоби в ККП начело с бъдещия премиер Джоу Ънлай, който счита, че пазарните сили не бива да се унищожават, а напротив – могат да се използват за целите на китайското благоденствие и еманципирането на страната както от Запада, така и от СССР.
Пред Мао Дзъдун стои нелеката задача да обедини тези две крила и затова създава своя визия, съгласно която съществуват няколко свята, поделящи се в три групи: суперсили (по това време САЩ и СССР), империалисти (Япония и Западна Европа) и трети свят начело с Китай. По същество тази теоретична постановка отразява древното китайско схващане за Пекин като център на познатия свят. Теорията за трите свята става ключова за развитието на Китай до смъртта на Мао, а движеща сила на китайската външна политика става Джоу Ънлай. След смъртта на Сталин Хрушчов осъжда теорията на Мао в частта ѝ, приравняваща Вашингтон с Москва, което води до китайско-съветската схизма.
Джоу Ънлай и Че Гевара по време на втората визита на Че Гевара в Китай през февруари 1965 г. Снимка: Creative Commons
След смъртта на Мао и мимолетното управление на Хуа Гуофън започва вторият етап във формирането на китайската външна политика, който е белязан от дънизма – системата от идеи, лансирана от новия китайски лидер Дън Сяопин.
Дънизмът заклеймява Културната революция и Големия скок напред като „двете големи грешки на Председателя Мао“, но не подлага на ревизия теорията за трите свята. На практика обаче външната политика на Дън е насочена към изграждането на стабилни връзки със САЩ и въвеждането на смесен тип икономика, която интегрира в себе си пазарни елементи.
Големият успех на Дън не е единствено бурното икономическо развитие на Китай, но и фактът, че Пекин и Вашингтон успяват да постигнат консенсус за отношенията между САЩ и Тайван. Така през 1979 г. американският президент Джими Картър едностранно прекратява договора за взаимна отбрана между Вашингтон и Тайпе. Иронично, но както историята често си прави шеги, Мао Дзъдун и Дън Сяопин успяват в това, в което хилядолетните императорски династии се провалят – обединението на Китай.
Дън Сяопин (в средата) и Националният комитет по американско-китайски отношения, Пекин, 1977 г. Снимка: Sumin Chou (On behalf of US-China Arts Exchange) / Creative Commons
Стъпвайки върху направеното от предшествениците им, следващите китайски лидери Дзян Дзъмин и Ху Дзинтао изграждат външнополитическата концепция за мирния възход на Китай (中国和平崛起). В резултат на нея страната успява да изгради привлекателен образ, своя мека сила, която води до превръщането ѝ във втората икономика в света.
Китайската външна политика в наши дни
За европееца и западния човек изобщо съвременен Китай може да бъде осмислен най-добре чрез понятието „стратегическа култура“, което обозначава системата от вярвания и идеи, залегнали в управлението и политиката на една страна. Периодът на управление на настоящия президент Си Дзинпин е ключов за това осмисляне, тъй като голяма част от идеите му са нови, макар че погрешно са приписвани на негови предшественици.
Това е и най-често срещаната грешка при анализа на системата от концепции, която носи името „Мисълта на Си Дзинпин“ (习近平新时代中国特色社会主义思想). Да се сравнява сегашният китайски лидер с Мао Дзъдун, бившите съветски лидери или пък с който и да е друг китайски политик е силно подвеждащо. Онова, което най-много отличава Си от предшествениците, е не начинът, по който управлява, или външната политика, която води, а неговото динамично разбиране за марксизма.
Идеята, че статичните категории на Маркс могат да бъдат обогатени и доразвити от конфуцианската диалектика, е ключова за мисълта на настоящия китайския президент.
Това е и първоизворът на неговите идеи за национално обединение на Китай, благоденствие на китайския народ и засилване на ролята на ККП като гарант за сигурността на страната. Това е и причината, поради която Си ревизира концепцията на предшественика си Ху Дзинтао за мирен възход на Китай (中国和平崛起), заменяйки го със своята доктрина за мирно развитие на страната (中国和平发展).
Ху Дзинтао и Барак Обама по време на срещата на Г-20 в Питсбърг през септември 2009 г. Снимка: Official White House, Pete Souza, Public domain, via Wikimedia Commons
Първият компонент е културното наследство на конфуцианството и даоизма. Идеите на Конфуций, че Китай е центърът на света – Поднебесната империя, която крепи вселената, – са политически екстраполирани в контекста на китайската доктрина за тиенся (天下) – създаването на система от отношения между Китай и останалите държави, в която всеки китаец допринася за благоденствието на китайския народ в политическо, културно и икономическо отношение.
Китайците, съгласно конфуцианските разбирания, са синовете на тази империя, която са призовани да населяват, съхранявайки нейната самобитна култура. Строгата йерархия в обществото се разглежда като гарант за ефективното му функциониране и за сигурността му, а поддържането на модерни и високотехнологични въоръжени сили – като необходимост за съществуването му.
Даоистката диалектика също има отношение към политическото развитие на Китай най-вече в частта, която насърчава всеки за самокултивиране в полза на обществото до превръщането на гражданина в сиен (仙) – съвършения човек, по подобие на древните божества в китайската митология. Идеята, че добрият гражданин спазва законите, не е чужда на западните школи, но в Китай тя се разглежда като необходимост, която произтича от философската потенция на човека да бъде съвършен.
Вторият компонент разглежда външнополитическото развитие на Китай като изконно свързано със социализма с китайски характеристики. В този смисъл политическите идеи на Си Дзинпин не ревизират постулатите на дънизма, а ги потвърждават с едно допълнение – че икономическите реформи в Китай не могат да бъдат съпътствани от политически, тъй като последните ще отслабят властта на ККП.
Схващането, че социализмът, макар и с китайски характеристики, трябва да остане социализъм, е червената линия, отвъд която Пекин разглежда всяко поставяне на този модел под въпрос като намеса във вътрешните му работи. По тази причина покойният вече държавен секретар на САЩ Хенри Кисинджър често съветваше политиците във Вашингтон да не поучават Китай по въпроси като човешките права, тъй като китайците го възприемат като намеса в политиката си. Всъщност самият Кисинджър има друго предвид: трудно може да убедиш държава с хилядолетния история, че моделът ѝ следва да бъде ревизиран. Това би имало обратния ефект; би изострило отношенията между Китай и Америка и всъщност точно това се случи.
Третият аспект от китайската външна политика се отнася до т.нар. военен патернализъм, провеждането на дълбоки реформи в Народната освободителна армия на Китай (НОАК) и изграждането на образа на „добрия войник“ чрез постигането на баланс в принципа „три правила за дисциплина и осем точки на внимание“ (三大纪律八项注意), които задават контурите на моралния облик на китайските въоръжени сили в очите на гражданите. Тук, разбира се, се добавя и стремежът на Пекин да разшири ядрения си арсенал като гарант за своя суверенитет. Това често се интерпретира от останалите ядрени сили като агресивна политика, насочена към надпревара във въоръжаването, но е факт, че Китай е единствената ядрена държава, която е възприела в своята доктрина принципа, че няма да използва ядрени оръжия първа (no-first-use policy).
Си Дзинпин и Джо Байдън, докато и двамата все още са вицепрезиденти. Снимка: David Lienemann, Public domain, via Wikimedia Commons
Стремежът към надпревара във въоръжаването трябва да се търси по-скоро в огромните усилия, които ККП положи, за да създаде високотехнологични оръжия за ранно реагиране в случай на вражеска атака, а не в грандиозни демонстрации и паради по подобие на руските.
На четвърто място следва да отбележим, че няма как да разберем китайската външна политика, без да изясним нейната концепция за разрешаване на конфликтите в глобален план. Тя е най-добре изразена от Фуданската школа и от нейния основател проф. Тан Шъпин, който посочва в своята теория, че когато между две държави съществува дилема на сигурността, не е задължително тя да прерасне в конфронтация. За разлика от реалистките теории (например тази на Греъм Алисън, която разглежда войната между една доминираща сила и нейния набиращ сила опонент като неизбежна), Тан представя алтернативен прочит, съгласно който конфликтът може да бъде избегнат, ако две държави хармонизират интересите си.
Виждаме такива опити при последните срещи между Си Дзинпин и Джо Байдън, а бъдещото развитие на американско-китайските отношения най-вероятно ще е големият тест за теориите на Алисън и на Тан.
Накрая, но не на последно място идва стремежът към национално обединение на Китай. Този момент е втората голяма червена линия за китайците както по отношение на Тайван, така и на Тибет. И тук причините не са чисто политически или стратегически. Във философски план това ни връща отново към конфуцианското разбиране, че всички китайци принадлежат към един народ и в този смисъл тяхното единство е дълг за всеки лидер.
В политически план и Тайван, и Тибет се разглеждат като част от Китай по силата на договореностите със САЩ и липсата на тайванско представителство в ООН. Но най-вече този стълб в китайската външна политика е отрицание на тайванската идея, че Тайпе, а не Пекин е центърът на китайското политическо цяло.
Големият тест за Китай: Европа
Ако САЩ бяха онези, които развиваха отношенията си с Китай в продължение на десетилетия и заедно с Пекин сдържаха СССР по време на Студената война, днес Европа е тази, която може да помогне на китайците да съхранят своето икономическо влияние в глобален план.
Съгласно китайската концепция за тиенся Европа представлява съвкупност от държави, които имат различна тежест в китайската външна политика в зависимост от икономическата си мощ и политическото си влияние. Така например Централна и Източна Европа имат много по-голямо значение за Китай от Западна Европа, тъй като те са мостът, чрез който инициативата „Един пояс – един път“ разпростира влиянието си на Стария континент.
Ако погледнем България, ще видим, че нашата страна е важен партньор за Пекин, тъй като Китай е третият по големина търговски партньор и втората по значимост дестинация за износ. Ето защо отношенията между двете държави бяха издигнати в ранг на стратегическо партньорство, а България беше изместена от графата „държава с нисък приоритет“ в „държава със среден приоритет“ за „Един пояс – един път“. Нещо повече, Централна и Източна Европа са важни за Китай, защото са част от друг регионален формат – 14+1, който гарантира свободен достъп на Пекин до европейските пазари.
Именно поради тази причина след началото на войната в Украйна Китай направи изрични договорки с Русия, че интересите му в региона не трябва да пострадат от действията на Москва. Можем убедено да кажем, че вакуумът, освободен от руското влияние в тези европейски държави постепенно започва да се запълва от Китай. За Европа ще е голям проблем да наложи червени линии на централно- и източноевропейците в отношенията им с Китай по две причини.
Първо, защото самият Европейски съюз е изключително зависим от китайската икономика и второ, защото всяко разкачване от Китай ще има сериозни щети конкретно върху икономиките на страните от Централна и Източна Европа. Държавите в еврозоната донякъде може и да избегнат или да смекчат тези ефекти, но не се знае какво ще се случи с България и Румъния например, които все още не се разплащат в евро.
Извън този приоритетен пояс попадат големите европейски икономики, като Франция, Италия и Германия, а също и държавите, които не са част от „Един пояс – един път“. Към тях Пекин има двустранен подход най-малкото защото те не могат да бъдат вместени в един огромен икономически проект. Франция винаги е била разглеждана като партньорска страна заради сравнително балансираните ѝ отношения със САЩ, а Германия – като силно зависима от Вашингтон държава, която, макар и икономически лидер на Европа, не може да разчупи американското влияние.
От другата страна са държави като Италия, която излезе от „Един пояс – един път“, или прибалтийските страни, които напуснаха инициативата 17+1, редуцирайки броя на участниците до 14. Отношението на Китай към тях беше достатъчно видимо при европейската обиколка на президента Си Дзинпин – той предпочете за свои спирки единствено Франция и Унгария. В този смисъл бъдещето на китайското влияние в тези страни много зависи от това дали Америка ще задържи доминиращата си роля в Европа, или ще се отдръпне. Факт е, че дори Франция не би могла да тушира ефектите от пълно икономическо разкачване с Китай, но поне докато Париж и Пекин се разплащат в евро или в долари, а не в юани, тези перспективи изглеждат далечни.
Третият пояс включва държави, които не са част от Европейския съюз и НАТО и по тази причина са потенциално най-близките партньори на Китай. Такъв пример е Сърбия, която винаги е спрягана за руското прокси на Балканите. Макар и осезаемо, руското влияние в Сърбия отдавна не е същото като преди. Откакто започна войната в Украйна, Белград бавно се еманципира от Русия и я замени с Китай – геополитическа трансформация, която придоби завършен вид със закупуването на китайски противоракетни системи.
Допълнителното задълбочаване на партньорските отношения между двете страни циментира статута на Сърбия като отправна точка за китайското присъствие на Балканите, а големият губещ от всичко това беше Русия, която нямаше какво да предложи на сръбските управляващи, тъй като всичките ѝ ресурси отиваха на фронта в Украйна. В перспектива китайското влияние в страната ще продължи да се засилва, докато напълно измести руското, а Москва ще остане просто като част от историческата памет на сърбите в контекста на нейните отношения с Пекин.
За Китай червените линии в отношенията с Европа са три: Тайванският въпрос, бъдещето на „Един пояс – един път“ и политическата реторика на европейските лидери по отношение на китайското управление. Или казано с други думи, отношението на Пекин към отделните държави ще зависи от това дали те следват политиката на единен Китай, дали участват в икономическите формати като „Един пояс – един път“ и до каква степен критикуват действията на китайското ръководство. Така ще бъде подредена и новата пирамида от интереси на Китай предвид нарастващата конкуренция със САЩ и опитите на Вашингтон да смекчи икономическите ефекти от войната в Украйна.
За разлика от Китай, Европейският съюз още не е очертал ясно своите червени линии, което създава впечатлението, че лидерите на Съюза не са единни в позициите си и не желаят отношенията с Пекин да бъдат решавани на общоевропейско равнище. Единствената последователна линия, следвана от Европа, всъщност е тази на САЩ, които припомнят на Китай, че не трябва да помага на Русия в Украйна.
За някои политици това е просто въпрос на политическо оцеляване, защото, ако икономиката на страните им рухне, те ще загубят позициите си. За други отношенията с Китай минават задължително през осмисляне на отношенията с Русия и САЩ. Но липсата на единство определено създава проблеми за Европа, защото, ако континентът е наясно какво да прави в отношенията си с Вашингтон и Москва, то за Пекин все още има сериозно колебание.
Китай от своя страна няма съюзници или врагове, защото неговата външнополитическа традиция не различава държавите като такива в смисъла, в който ги разбират например САЩ и Европа. Това затруднява Запада в неговата визия за бъдещето на отношенията му с Пекин най-малкото защото шахматната дъска, на която фигурите се делят на черни и бели, на добри и лоши, съществено се различава от геополитическата дихотомия Ин – Ян, изключваща оцветяването на отсрещната страна в едноцветни краски и морални категории.
Затова колкото и трудно да е, на Европа може да ѝ се наложи да разбере Китай в смисъла, в който го разбираше Хенри Кисинджър по време на Студената война. Неслучайно в своите трудове Патриархът на американската дипломация описва Китай като острието на триъгълника, което балансира отношенията между глобалните актьори. И ако ЕС иска да стане част от този триъгълник, използването на острието ще бъде необходимост.
България е като заседнал в плитчина кораб, който не може да бъде изкаран оттам – няма вятър и приливи, няма връзка с пристанищните власти, нито мощни буксири, които да го изтеглят. Няма кой да оцени колко е заседнал, да определи местоположението и условията на дъното, да провери корпуса и пораженията върху плавателния съд и товара му.
Няма екипаж и пътници, които да искат да останат на такъв кораб, където ги чака несигурно бъдеще и сигурна смърт. Икономическата миграция и демографската криза си имат своите „кръстници“ – политиците. Развитието на България е парализирано именно от тях.
Пораженията на политическата непригодност
Задълбочаването на политическата криза блокира държавата. Постоянните избори и смяна на правителства – в момента управлява седмото за три години – създават усещане за застой наред с невъзможността да се установи последователност в управлението и дългосрочна визия.
Партиите са неспособни да постигнат консенсус по ключови въпроси и това е не просто обезсърчаващо, а пагубно за хиляди българи. Жертва на управленската непригодност стана и Планът за възстановяване и устойчивост (ПВУ), по който България, освен че единствена в ЕС е получила само един транш от общо четири плащания, отново единствена не е предала главата за енергетиката – REPowerEU, въпреки трикратното настояване от страна на Европейската комисия.
Ако го беше направила до края на декември 2023 г., щеше да получи 20% авансово плащане от втория транш по ПВУ в размер на 653 млн. евро. Искането за второто плащане е изпратено преди половин година, но все още е на етап оценка. Сега Министерството на финансите спешно събира проекти за подобряване на енергийната ефективност, въвеждане на транспорт с нулеви емисии, намаляване на въглеродния отпечатък, справяне с енергийната бедност и др.
В ПВУ е големият шанс за България, тъй като тези 4,4 млрд. евро се отпускат срещу реформи и така държавата би могла да извърши трансформация – икономическа, социална, енергийна, но е застрашена от загубата им.
За тази опасност предупреди Илияна Цанова, заместник генерален директор на направление „Бюджет“ в Европейската комисия, в интервю за БНР.
Остават още 2 години срок, в който България може да инвестира 9 млрд. лв. по ПВУ, който ресурс е ключов за модернизацията на българската икономика за превключване на много по-висока скорост. И рискът тези пари да бъдат загубени е много сериозен, защото единственото плащане е направено през декември 2022 г.
А до 2026 г. всички проекти по ПВУ трябва да са готови и разходите – верифицирани. Но за да се стигне до този етап, България трябва да получи средствата, а за да ги получи – да свърши несвършеното от 49-тия парламент.
Ако тези законопроекти не бъдат приети, ще бъде намалено второто плащане и тази сума няма да се възстанови, дори и да бъдат гласувани по-късно:
приемане на второ четене на закона за личния фалит;
промени в закона за защита на подаващите сигнали, за да се включат в него и сигналите отпреди 2021 г.;
процедурни правила за избор на членове на Антикорупционната комисия;
одобрение от Народното събрание на актуализираната пътна карта на България за климатична неутралност;
промени в Закона за съдебната власт, чрез който да се даде възможност на ВСС и на Висшия прокурорски съвет да променят етичните кодекси на съдиите и на прокурорите.
Освен втория транш България не е получила нито едно евро от Фонда за справедлив преход. Tериториалните планове на трите въглищни региона Стара Загора, Перник и Кюстендил, които очакват общо 1,2 млрд. евро, са одобрени. Но държавата не е представила график за затваряне на въглищните централи, освен крайната дата 2038 г., а ЕК настоява да го види в пътната карта за климатична неутралност. С отлагането на либерализацията на електроенергийния пазар политиците оставиха на изкуствено дишане за една година тецовете и мините, но това не решава генералния проблем с поминъка на хората после, а също и с бъдещето на трите региона.
Скъпият (заради високите цени на въглеродните емисии) ток от въглища се купува все по-малко и най-вероятно централите ще спрат преди 2038 г. Заради страха си от яростни протести политиците така и не вземат очакваното от тях крайно решение какво ще стане с въглищата. И вместо на реализъм го удрят на популизъм или бягство от темата.
Политическата криза, чиито последствия са непрекъсната смяна на администрацията и управленска немощ, сериозно забавя и усвояването на европейските фондове. Едва 4,6% от средствата, които ЕС дава на България чрез еврофондовете за периода 2021–2027 г., са усвоени, съобщи в Народното събрание служебната финансова министърка Людмила Петкова. От общо 12,9 млрд. евро са усвоени едва 616 млн. евро към средата на програмния период.
Къде отива стратегическата цел?
Засядането на държавата в плитчините на политическата криза блокира и икономиката. Нестабилността намали и привлекателността на България за чуждестранните инвеститори (наред с края на мантрата за ниските заплати), а също доведе и до забавяне на икономическия растеж. За 2023 г. икономиката нарасна с 1,8% – най-ниският резултат от 2014 г. насам, когато се срина Корпоративна търговска банка. България губи своята конкурентоспособност в регионален и глобален мащаб поради икономически проблеми и липса на стратегически инвестиции.
Но най-голямата жертва на политическата непригодност стана пътят към еврото. Страната ни изпусна възможността да се присъедини на 1 януари 2025. Според конвергентните доклади на Европейската комисия и на Европейската централна банка (ЕЦБ) причината е в неизпълнение на един-единствен от четирите критерия – за инфлацията. Тя остава по-висока от допустимата за еврозоната референтна стойност – да не надвишава с повече от 1,5% средногодишната в трите държави с най-ниска инфлация.
Поскъпването е резултат от фискална експанзия според гуверньора на БНБ Димитър Радев, но също и от кредитна, която БНБ не смята за нужно да регулира. Има обаче и друго, което посочва само ЕЦБ – проблемът с поставянето на България през октомври 2023 г. в „сивия списък“ на глобалния надзорен орган Financial Action Task Force (FATF) за пране на пари. Следващият доклад, на който се разчита да извади България от компрометиращия списък, е през есента на 2025 г.
Въпреки спирачките за еврото депутати от разпадналата се сглобка – ГЕРБ, ДПС и ПП–ДБ, защитиха възможността да имаме решение за присъединяване към еврозоната в средата на 2025-та, за да приемем единната валута от 1 януари 2026 г.
Особено настъпателен беше заместник-председателят на парламентарната група на ДПС Йордан Цонев.
Ние предварително знаехме, че юнският доклад ще бъде негативен по отношение на инфлацията, тъй като това е процес, който не може да бъде коригиран в рамките на няколко месеца или на половин година. През септември-октомври ще има ъпдейтване на този доклад и тогава ние ще сме покрили критерия, и лошата новина за вас е, че България ще получи решение за въвеждане на еврото догодина юни и ще го въведе на 1 януари 2026 г.
Но това съвсем не е сигурно. Най-големият оптимист се оказа гуверньорът на БНБ Димитър Радев, който в интервю за БТА заяви, че България би могла да въведе еврото и догодина при „намаляване на фискалната експанзия и намаляване на бюджетния дефицит през настоящата година с около 1% от БВП“, както и при „проевропейско правителство с достатъчно широка подкрепа и хоризонт на действие“.
Все още не е известно какво правителство ще се състави, но едно е сигурно – и да го има, устойчивост и дълъг хоризонт няма да са неговите характеристики. А БНБ не за първи път препоръчва по-нисък дефицит. Направи го още докато се обсъждаше в парламента бюджет 2024, където заложеният касов дефицит е 5,9 млрд. лв., или 3% от БВП. След мисията си през март за понижение на дефицита с 1% настоя и МВФ, както и за реформи за повишаване на приходите и като цяло за разумна фискална политика.
Но дори и в най-добрата за България хипотеза, в която извънредните конвергентни доклади са положителни, а решението за еврозоната бъде обявено в средата на 2025 г., за да се присъединим шест месеца по-късно, има рискове. През това време партии като БСП, „Възраждане“, „Величие“, ИТН, не без помощта на президентската институция и руските хибридни атаки, ще правят всичко по силите си, за да попречат на този процес. Политическа нестабилност, подсилена с краен популизъм, е една от рецептите, а мнозинство, което да ѝ се противопостави, няма.
Засега България остава в средата на нищото. И екипажът е негоден да я помръдне.
You can now create a pool of non-persistent virtual desktops using Amazon WorkSpaces and share them across a group of users. As the desktop administrator you can manage your entire portfolio of persistent and non-persistent virtual desktops using one GUI, command line, or set of API-powered tools. Your users can log in to these desktops using a browser, a client application (Windows, Mac, or Linux), or a thin client device.
Amazon WorkSpaces Pools (non-persistent desktops) WorkSpaces Pools ensures that each user gets the same applications and the same experience. When the user logs in, they always get access to a fresh WorkSpace that’s based on the latest configuration for the pool, centrally managed by their administrator. If the administrator enables application settings persistence for the pool, users can configure certain application settings, such as browser favorites, plugins, and UI customizations. Users can also access persistent file or object storage external to the desktop.
These desktops are a great fit for many types of users and use cases including remote workers, task workers (shared service centers, finance, procurement, HR, and so forth), contact center workers, and students.
As the administrator for the pool, you have full control over the compute resources (bundle type) and the initial configuration of the desktops in the pool, including the set of applications that are available to the users. You can use an existing custom WorkSpaces image, create a new one, or use one of the standard ones. You can also include Microsoft 365 Apps for Enterprise on the image. You can configure the pool to accommodate the size and working hours of your user base, and you can optionally join the pool to your organization’s domain and active directory.
Getting started Let’s walk through the process of setting up a pool and inviting some users. I open the WorkSpaces console and choose Pools to get started:
I have no pools, so I choose Create WorkSpace on the Pools tab to begin the process of creating a pool:
The console can recommend workspace options for me, or I can choose what I want. I leave Recommend workspace options… selected, and choose No – non-persistent to create a pool of non-persistent desktops. Then I select my use cases from the menu and pick the operating system and choose Next to proceed:
The use case menu has lots of options:
On the next page I start by reviewing the WorkSpace options and assigning a name to my pool:
Next, I scroll down and choose a bundle. I can pick a public bundle or a custom one of my own. Bundles must use the WSP 2.0 protocol. I can create a custom bundle to provide my users with access to applications or to alter any desired system settings.
Moving right along, I can customize the settings for each user session. I can also enable application settings persistence to save application customizations and Windows settings on a per-user basis between sessions:
Next, I set the capacity of my pool, and optionally establish one or more schedules based on date or time. The schedules give me the power to match the size of my pool (and hence my costs) to the rhythms and needs of my users:
If the amount of concurrent usage is more dynamic and not aligned to a schedule, then I can use manual scale out and scale in policies to control the size of my pool:
I tag my pool, and then choose Next to proceed:
The final step is to select a WorkSpaces pool directory or create a new one following these steps. Then, I choose Create WorkSpace pool.
After the pool has been created and started, I can send registration codes to users, and they can log in to a WorkSpace:
I can monitor the status of the pool from the console:
Things to know Here are a couple of things that you should know about WorkSpaces Pools:
Programmatic access – You can automate the setup process that I showed above by using functions like CreateWorkSpacePool, DescribeWorkSpacePool, UpdateWorkSpacePool, or the equivalent AWS command line interface (CLI) commands.
Regions – WorkSpaces Pools is available in all commercial AWS Regions where WorkSpaces Personal is available, except Israel (Tel Aviv), Africa (Cape Town), and China (Ningxia). Check the full Region list for future updates.
Amazon DataZone is a data management service to catalog, discover, analyze, share, and govern data between data producers and consumers in your organization. Engineers, data scientists, product managers, analysts, and business users can easily access data throughout your organization using a unified data portal so that they can discover, use, and collaborate to derive data-driven insights.
Now, I am excited to announce in preview a new API-driven and OpenLineage compatible data lineage capability in Amazon DataZone, which provides an end-to-end view of data movement over time. Data lineage is a new feature within Amazon DataZone that helps users visualize and understand data provenance, trace change management, conduct root cause analysis when a data error is reported, and be prepared for questions on data movement from source to target. This feature provides a comprehensive view of lineage events, captured automatically from Amazon DataZone’s catalog along with other events captured programmatically outside of Amazon DataZone by stitching them together for an asset.
When you need to validate how the data of interest originated in the organization, you may rely on manual documentation or human connections. This manual process is time-consuming and can result in inconsistency, which directly reduces your trust in the data. Data lineage in Amazon DataZone can raise trust by helping you understand where the data originated, how it has changed, and its consumption in time. For example, data lineage can be programmatically setup to show the data from the time it was captured as raw files in Amazon Simple Storage Service (Amazon S3), through its ETL transformations using AWS Glue, to the time it was consumed in tools such as Amazon QuickSight.
With Amazon DataZone’s data lineage, you can reduce the time spent mapping a data asset and its relationships, troubleshooting and developing pipelines, and asserting data governance practices. Data lineage helps you gather all lineage information in one place using API, and then provide a graphical view with which data users can be more productive, make better data-driven decisions, and also identify the root cause of data issues.
Let me tell you how to get started with data lineage in Amazon DataZone. Then, I will show you how data lineage enhances the Amazon DataZone data catalog experience by visually displaying connections about how a data asset came to be so you can make informed decisions when searching or using the data asset.
Getting started with data lineage in Amazon DataZone In preview, I can get started by hydrating lineage information into Amazon DataZone programmatically by either directly creating lineage nodes using Amazon DataZone APIs or by sending OpenLineage compatible events from existing pipeline components to capture data movement or transformations that happens outside of Amazon DataZone. For information about assets in the catalog, Amazon DataZone automatically captures lineage of its states (i.e., inventory or published states), and its subscriptions for producers, such as data engineers, to trace who is consuming the data they produced or for data consumers, such as data analyst or data engineers, to understand if they are using the right data for their analysis.
With the information being sent, Amazon DataZone will start populating the lineage model and will be able to map the identifier sent through the APIs with the assets already cataloged. As new lineage information is being sent, the model starts creating versions to start the visualization of the asset at a given time, but it also allows me to navigate to previous versions.
I use a preconfigured Amazon DataZone domain for this use case. I use Amazon DataZone domains to organize my data assets, users, and projects. I go to the Amazon DataZone console and choose View domains. I choose my domain Sales_Domain and choose Open data portal.
I enter “Market Sales Table” in the Search Assets bar and then go to the detail page for the Market Sales Table asset. I choose the LINEAGE tab to visualize lineage with upstream and downstream nodes.
I can now dive into asset details, processes, or jobs that lead to or from those assets and drill into column-level lineage.
Interactive visualization with data lineage I will show you the graphical interface using various personas who regularly interact with Amazon DataZone and will benefit from the data lineage feature.
First, let’s say I am a marketing analyst, who needs to confirm the origin of a data asset to confidently use in my analysis. I go to the MarketingTestProject page and choose the LINEAGE tab. I notice the lineage includes information about the asset as it occurs inside and out of Amazon DataZone. The labels Cataloged, Published, and Access requested represent actions inside the catalog. I expand the market_sales dataset item to see where the data came from.
I now feel assured of the origin of the data asset and trust that it aligns with my business purpose ahead of starting my analysis.
Second, let’s say I am a data engineer. I need to understand the impact of my work on dependent objects to avoid unintended changes. As a data engineer, any changes made to the system should not break any downstream processes. By browsing lineage, I can clearly see who has subscribed and has access to the asset. With this information, I can inform the project teams about an impending change that can affect their pipeline. When a data issue is reported, I can investigate each node and traverse between its versions to dive into what has changed over time to identify the root cause of the issue and fix it in a timely manner.
Finally, as an administrator or steward, I am responsible for securing data, standardizing business taxonomies, enacting data management processes, and for general catalog management. I need to collect details about the source of data and understand the transformations that have happened along the way.
For example, as an administrator looking to respond to questions from an auditor, I traverse the graph upstream to see where the data is coming from and notice that the data is from two different sources: online sale and in-store sale. These sources have their own pipelines until the flow reaches a point where the pipelines merge.
While navigating through the lineage graph, I can expand the columns to ensure sensitive columns are dropped during the transformation processes and respond to the auditors with details in a timely manner.
Join the preview Data lineage capability is available in preview in all Regions where Amazon DataZone is generally available. For a list of Regions where Amazon DataZone domains can be provisioned, visit AWS Services by Region.
Data lineage costs are dependent on storage usage and API requests, which are already included in Amazon DataZone’s pricing model. For more details, visit Amazon DataZone pricing.
In this release, we updated the implementation guidance for the new and existing best practices to be more prescriptive. This includes enhanced recommendations and steps on reusable architecture patterns focused on specific business outcomes.
A brief history
The Well-Architected Framework is a collection of best practices that allow customers to evaluate and improve the design, implementation, and operations of their workloads in the cloud.
In 2020, we released the new version of the Well-Architected Framework guidance, more lenses, and an API integration with the AWS Well-Architected Tool. We added the sixth pillar, Sustainability, in 2021. In 2022, dedicated HTML pages were introduced for each consolidated best practice across all six pillars, with several best practices updated with improved prescriptive guidance. By December 2023, we improved more than 75% of the Framework’s best practices. As of June 2024, more than 95% of the Framework’s best practices have been refreshed at least once.
What’s new
The Well-Architected Framework supports customers as they mature in their cloud journey by providing guidance to help achieve accurate business, environment, and workload solutions. Well-Architected is committed to providing such information to customers by continually evolving and updating our guidance.
In the Operational Excellence Pillar, we updated 30 best practices across six questions. This includes OPS01, OPS02, OPS03, OPS07, OPS10, and OPS11. This update includes a refreshed structure and improved prescriptive guidance with updates on observability, generative AI capabilities, operating models, and the evolution of operational practices.
As part of this update, we consolidated four best practices into two (OPS01-BP07 merged into OPS01-BP06, OPS03-BP08 merged into OPS03-BP04) and changed the titles of seven best practices. Additionally, we added one new design principal to highlight the importance of aligning operating models to business outcomes and reordered design principles according to their priority from foundational to specialized. We updated three design principles and changed the title of one design principle. We’ve also updated the operating model guidance section of the pillar to be more prescriptive, showcasing pathways to evolving operating models.
The implementation guidance in best practices includes guidance on implementing generative AI capabilities with Amazon Q (Q Developer, Q Business, Q in QuickSight), the latest capabilities from Amazon CloudWatch Network Monitor, Amazon CloudWatch Internet Monitor, Amazon CloudWatch Logs, Amazon CloudWatch best practice alarms, cross-account observability, log-based alarms, log data protection, and AWS Health.
Security
In the Security Pillar, we updated 28 best practices across 10 questions. This includes SEC01, SEC02, SEC03, SEC04, SEC05, SEC06, SEC07, SEC08, SEC09, and SEC10. Best practice updates include removing duplication, clarifying desired outcomes, and providing robust prescriptive implementation guidance. As part of this update, we merged SEC01-BP05 into SEC01-BP04. We deleted two practices, SEC08-BP05 and SEC09-BP03, to remove the duplication of guidance covered across other existing practices. We updated the titles for 14 practices and changed the order of nine practices to improve clarity and flow.
Reliability
In the Reliability Pillar, we updated 11 best practices across six questions. This includes REL02, REL04, REL05, REL06, REL07, and REL08, with three best practices changing titles including REL04-BP01, REL05-BP06, and REL06-BP05. We improved resources available in best practices to include more recent blog posts, technical talks, and presentations. We also improved the prescriptive guidance by expanding on implementation steps. New services and service features added to the best practices guidance for AWS Resilience Hub, Amazon Route 53, Amazon Route53 Application Recovery Controller, AWS Fault Injection Service, and Amazon CloudWatch Synthetics.
Performance Efficiency
In the Performance Efficiency Pillar, we updated nine best practices across three questions. This includes PERF01, PERF03, and PERF05. We improved the prescriptive guidance on these best practices and added pillar-specific guidance on services including Amazon Devops Guru and Amazon ElastiCache Serverless. We’ve updated the resources section of all best practices with new and relevant resources.
Cost Optimization
In the Cost Optimization Pillar, we updated eight best practices across five questions. This includes COST01, COST02, COST03, COST05, and COST11. One new best practice added in COST06 highlights the benefits of using shared resources for organizational cost optimization. The improved best practices include guidance on AWS services and features including the AWS Cost Optimization Hub, AWS Billing and Cost Management features, and AWS Data Exports. These updates also cover sample key performance indicators (KPIs) for tracking optimization efforts, elaborate on the use of cost allocation tags, and discuss the split cost allocation for Amazon EKS and Amazon ECS to separate costs of containerized workloads. Additionally, the updates offer improved prescriptive and clear guidance on budgeting and forecasting. Finally, you’ll find guidance on using automations to reduce costs.
Sustainability
In the Sustainability Pillar, we updated 18 best practices across five questions. This includes SUS01, SUS02, SUS03, SUS04, SUS05, and SUS06. We improved the prescriptive guidance on these best practices, and added Pillar-specific guidance on services, including AWS Local Zones, AWS Outposts, Amazon Chime, AWS Wickr, Amazon CodeWhisperer, and AWS Customer Carbon Footprint Tool. We’ve expanded lists of resources across all best practices with new and relevant resources.
Conclusion
This release includes updates and improvements to the Framework guidance totaling 105 best practices. As of this release, we’ve updated 95% of the existing Framework best practices at least once since October 2022. With this release, we have refreshed 100% of the Operational Excellence, Security, Performance Efficiency, Cost Optimization, and Sustainability Pillars, as well as 79% of Reliability Pillar best practices. Best practice updates in this release across Operational Excellence, Security, and Reliability (a total of 66) are first-time updates since major Framework improvements started in 2022.
The content is available in 11 languages: English, Spanish, French, German, Italian, Japanese, Korean, Indonesian, Brazilian Portuguese, Simplified Chinese, and Traditional Chinese.
Updates in this release are also available in the AWS Well-Architected Tool, which you can use to review your workloads, address important design considerations, and help you follow the AWS Well-Architected Framework guidance.
Doug Rabson began by providing an overview of the current state of
FreeBSD support for OCI containers, noting that while FreeBSD has long
supported containers through its jail and vnet features, the ecosystem
around OCI containers requires further development. “FreeBSD has been
able to do containers for a long time, but we need to align better
with OCI standards to make our containers more compatible and easier
to use,” Rabson remarked.
AWS Certificate Manager (ACM) is a managed service that you can use to provision, manage, and deploy public and private TLS certificates for use with Elastic Load Balancing (ELB), Amazon CloudFront, Amazon API Gateway, and other integrated AWS services. Starting August 2024, public certificates issued from ACM will terminate at the Starfield Services G2 (G2) root with subject C=US, ST=Arizona, L=Scottsdale, O=Starfield Technologies, Inc., CN=Starfield Services Root Certificate Authority – G2 as the trust anchor. We will no longer cross sign ACM public certificates with the GoDaddy operated root Starfield Class 2 (C2) with subject C=US, O=Starfield Technologies, Inc., OU=Starfield Class 2 Certification Authority.
Background
Public certificates that you request through ACM are obtained from Amazon Trust Services. Like other public CAs, Amazon Trust Services CAs have a structured trust hierarchy. A public certificate issued to you, also known as the leaf certificate, chains to one or more intermediate CAs and then to the Amazon Trust Services root CA.
The Amazon Trust Services root CAs 1 to 4 are cross signed by the Amazon Trust Services root Starfield Services G2 (G2) and further by the GoDaddy operated Starfield Class 2 root (C2). The cross signing was done to provide broader trust because Starfield Class 2 was widely trusted when ACM was launched in 2016.
What is changing?
Starting August 2024, the last certificate in an AWS issued certificate chain will be one of Amazon Root CAs 1 to 4 where the trust anchor is Starfield Services G2. Currently, the last certificate in the chain that is returned by ACM is the cross-signed Starfield Services G2 root where the trust anchor could be Starfield Class 2, as shown in Figure 1 that follows.
Current chain
Figure 1: Certificate chain for ACM prior to August 2024
New chain
Figure 2 shows the new chain, where the last certificate in an AWS issued certificate’s chain is one of the Amazon Root CAs (1 to 4), and the trust anchor is Starfield Services G2.
Figure 2: New certificate chain for ACM starting on August 2024
Why are we making this change?
Starfield Class 2 is operated by GoDaddy, and GoDaddy intends to deprecate C2 in the future. To align with this, ACM is removing the trust anchor dependency on the C2 root.
How will this change impact my use of ACM?
We don’t expect this change to impact most customers. Amazon owned trust anchors have been established for over a decade across many devices and browsers. The Amazon owned Starfield Services G2 is trusted on Android devices starting with later versions of Gingerbread, and by iOS starting at version 4.1. Amazon Root CAs 1 to 4 are trusted by iOS starting at version 11. A browser, application, or OS that includes the Amazon or Starfield G2 roots will trust public certificates obtained from ACM.
What should you do to prepare?
We expect the impact of removing Starfield Services C2 as a trust anchor to be limited to the following types of customers:
To resolve this, you can add the Amazon CAs to your trust store.
Customers who pin to the cross-signed certificate or the certificate hash of Starfield Services G2 rather than the public key of the certificate.
Certificate pinning guidance can be found in the Amazon Trust repository.
Customers who have taken a dependency on the chain length. The chain length for ACM issued public certificates will reduce from 3 to 2 as part of this change.
Customers who have a dependency on chain length will need to update their processes and checks to account for the new length.
Customers can test that their clients are able to open the Valid test certificates from the Amazon Trust Repository.
FAQs
What should I do if the Amazon Trust Services CAs aren’t in my trust store?
If your application is using a custom trust store, you must add the Amazon Trust Services root CAs to your application’s trust store. The instructions for doing this vary based on the application or service. Refer to the documentation for the application or service that you’re using.
If your tests of any of the test URLs failed, you must update your trust store. The simplest way to update your trust store is to upgrade the operating system or browser that you’re using.
The following operating systems use the Amazon Trust Services CAs:
Amazon Linux (all versions)
Microsoft Windows versions, with updates installed, from January 2005, Windows Vista, Windows 7, Windows Server 2008, and later versions
Mac OS X 10.4 with Java for Mac OS X 10.4 Release 5, Mac OS X 10.5, and later versions
Red Hat Enterprise Linux 5 (March 2007 release), Linux 6, and Linux 7 and CentOS 5, CentOS 6, and CentOS 7
Ubuntu 8.10
Debian 5.0
Java 1.4.2_12, Java 5 update 2 and all later versions, including Java 6, Java 7, and Java 8
Modern browsers trust Amazon Trust Services CAs. To update the certificate bundle in your browser, update your browser. For instructions on how to update your browser, see the update page for your browser:
The Windows operating system manages certificate bundles for Internet Explorer and Microsoft Edge, so to update your browser, you must update Windows.
Why does ACM have to change the trust anchor? Why can’t ACM continue to vend certificates cross signed with C2?
There are some rare clients who check for the validity of all the certificates in the certificate chain returned by an endpoint even when they have a shorter-path trust anchor. If ACM continues to return the chain with the G2 root cross signed by C2, such clients might check the CRL and OCSP issued by Starfield Class 2. These clients will see failures on CRL and OCSP lookup chain after the expiry of the CRLs or OCSP responses issued by Starfield Class 2.
When will GoDaddy deprecate the Starfield Class 2 root?
GoDaddy has not announced specific dates for deprecation of the Starfield Class 2 root. We are working with GoDaddy to minimize customer impact.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Certificate Manager re:Post or contact AWS Support.
„Икономиката, глупако!“ Думите принадлежат на Джеймс Карвил, съветник на Бил Клинтън по време на президентската му кампания срещу Джордж Буш-старши през 1992 г. Фразата е широко позната в САЩ, защото се приема, че обяснява простичко мисленето на американския избирател: най-важна е икономиката.
И през 2024 г. 73% от американците посочват икономиката като приоритет. Логиката е, че икономическият растеж води до повишаване на индивидуалното богатство и стандарт на живот. Това мислене е основна жилка в американската представа за света. Ето защо в политиката преобладава убеждението, че ако един президент изпусне икономиката, значи е изгубил изборите.
Трудният мандат на Джо Байдън
През 2021 г. Джо Байдън пое президентството в разгара на пандемията и началото на дългосрочни проблеми със световната верига на доставки, които започнаха да оказват влияние към средата и края на 2022 г. Отпуснатите от Байдън помощи в периода на пандемията и фактът, че хората прекарваха повече време у дома, както и последвалото „отваряне“ предизвикаха ръст в харченето и към края на 2022 г. все още беше трудно за обикновения човек да разбере, че живее в кризисни, „безпрецедентни“ времена.
Това се промени в хода на 2023 г., когато проблемите с доставките най-накрая се отразиха върху цените, а корпорациите използваха случая, за да вдигнат и задържат високите цени – феномен, който все по-често е наричан greedflation, букв. „алчна инфлация“. Множество проучвания показват, че корпоративна Америка и най-богатите са пожънали огромни печалби от началото на пандемията насам, докато животът на онези, които бяха наричани „незаменими“ работници, се влошава.
Икономическата политика на Джо Байдън предлага смели решения с потенциално добри резултати – безработицата е рекордно ниска, достъпът до здравеопазване се разширява, налице са инвестиции в ключови сектори, като научноизследователска и развойна дейност, производство, строителство. Проблемът в момента е, че поради високата инфлация, наследена от пандемията, и последвалите военни конфликти, като този в Украйна, възприятията на обществото са различни от данните.
Надежда има и в поредицата от съдебни искове, заведени от администрацията на Байдън срещу големи компании, включително от Силициевата долина, за нарушаване на антимонополното законодателство. Тези правни казуси тепърва ще бъдат разрешавани, някои от тях вероятно ще стигнат и до Върховния съд. Ако решенията са в полза на потребителите, ефектите от тях ще траят много след края на мандата на Байдън, тъй като – за разлика от президентските укази – не могат да бъдат отменени от неговия наследник. Основният проблем за Байдън като кандидат е как комуникира тези усилия с избирателите си, голяма част от които го виждат просто като по-малкото зло и компромисен кандидат, както вече писахме.
Президентът Байдън подписва указ за овладяване на инфлацията на 16 август 2022 г. В мерките са включени намаляване на бюджетните разходи и на цените на лекарствата, както и инвестиции в националната енергетика и зелената енергия. Снимка: The White House, Public domain / Wikimedia Commons
В рамките на настоящата си кампания Байдън обещава да продължи с усилията в тази посока, да предложи още политики в подкрепа на средната класа, да осигури достъпно здравеопазване и да продължи инвестициите в инфраструктура. За да бъдат въведени тези промени обаче, президентът трябва да има подкрепа в Конгреса. Дори всичко това да е налице, пак има риск законопроектите да бъдат блокирани от съдебната система, както в случая с опрощаването на студентските заеми или със законодателството в полза на правата на работниците. Остава въпросът и колко смели и визионерски могат да бъдат политиките на умерен кандидат като Джо Байдън във време, в което все повече американци смятат, че множество системи се нуждаят от основен ремонт.
Ще свърши ли късметът на Тръмп?
Голяма част от това усещане се канализира от Доналд Тръмп още през 2016 г., когато се позиционира като „антисистемен“ и силно реформаторски настроен кандидат. При встъпването си в длъжност Тръмп наследи една от най-силните икономики в историята на страната. Талантът на 45-тия да не казва нищо, докато не спира да говори, както и да си приписва всяко постижение и да очерня опонентите си за всяка своя грешка, в допълнение към имиджа му на бизнесмен, поддържат популярността му сред различни сегменти на обществото, за които икономиката е приоритет.
Фактите обаче са малко по-различни. По време на първия си мандат Тръмп обеща и не изпълни следните икономически политики:
Растеж на икономиката с 4% годишно (икономиката продължи да расте със същите стойности както по времето на втория мандат на Барак Обама).
Намаляване на външния дълг или цялостното му елиминиране (дълговете, натрупани от администрацията на Тръмп, ще тежат на икономиката с години, смятат експерти).
Намаляване на дефицита в търговския баланс (също достигнал рекордни нива по време на управлението на Тръмп).
„Връщане“ на индустрията и производството в САЩ (това, както и друга популярна опорна точка на Тръмп – депортиране на нелегалните имигранти, които са огромна част от работната ръка в страната – противоречат на принципите на печалбата, изповядвани понастоящем от корпоративна Америка. Най-пресният пример е компанията Deer, известна с тракторите и земеделските си машини, която изнася производството си в Мексико и съкращава американските си работници).
Намаляване на данъците за средната класа, което да не доведе до дефицит или до натрупване на дълг (реформите на Тръмп бяха в полза на най-заможните, а бюджетният дефицит достигна рекордни стойности през 2020 г.).
Списъкът може да бъде продължен. Ставащото в икономически план винаги се усеща след година-две; повечето избиратели обаче живеят в настоящето. Това, че част от тях приписват трудните времена директно на Джо Байдън, в комбинация с непрестанната очерняща кампания, която се лее от консервативни медии като „Фокс Нюз“, може да помогне на Тръмп да спечели втори мандат с обещание да стабилизира икономиката. Въпросът е кога и дали ще свърши късметът на Тръмп. Или поне кривите огледала, през които пречупва света. А обещанията си остават същите: масови депортации, орязване на данъците и корпоративните налози, вдигане на митата, по-евтино електричество от въгледобив с данъчни облекчения за производителите на изкопаеми горива.
Прилики и разлики
Данъчните облекчения за изкопаеми горива на Тръмп може да изглеждат абсурдни в ерата на климатичните промени и все по-екстремното време, но износът на горива така или иначе достигна рекордни нива по време на администрацията на… Джо Байдън. Действителността е доста по-сложна от телевизионен дебат или двуцветна идеология. А решенията на истинските проблеми обикновено са далеч от партизанщината.
Джо Байдън пренасочи огромна част от федералните средства към индустрията, инфраструктурата и възобновяемите източници на енергия, но инфлацията след пандемията попречи на избирателите да усетят ефекта от политиките му. Ако някой ще пожъне ползи от тях, то това ще е носителят на следващия мандат.
Новосъздадени работни места по времето на президентите Картър, Байдън, Клинтън, Рейгън, Обама, Буш-старши, Буш-младши и Тръмп. Графика: Farcaster, CC BY-SA 4.0 https://creativecommons.org/licenses/by-sa/4.0 / Wikimedia Commons
Въпреки че Тръмп подкрепя класически консервативни икономически политики, като намаляване на данъците например, увеличаването на митата и противопоставянето му на глобализирането на икономиката и на износа на работна ръка са в противоречие с ортодоксалните разбирания на партията. Самата партия обаче се е превърнала в култ към личността на 45-тия президент, така че надали може да се очаква съпротива. Във всички случаи политическата некомпетентност на Тръмп не бива да се бърка с реалните проблеми, към които той се нагажда и които експлоатира.
Третият най-важен проблем, посочен от американците, е намаляването на влиянието на парите върху политиката (62% отговарят, че това е основен приоритет за тях). Съвсем легитимен въпрос за много американци е доколко може да се очаква от който и да е кандидат да направи спешни и нужни реформи, свързани с климата, технологиите или данъците, когато донори на кампаниите са петролни магнати, технологични компании и милиардери. Този въпрос важи за промените във всяка сфера, посочена като важна от избирателите – здравеопазване, образование, енергетика, транспорт…
Очакваният сблъсък
На 27 юни започват президентските дебати. Генералният директор на Си Ен Ен (телевизията с монопол върху юнския дебат) неслучайно нарича събитието „шоу“, а кандидат-президентите – „звезди“. Дебатът надали ще промени мнението на твърдия електорат, а е по-скоро ритуална традиция, която се третира точно като такава от всички участници и обещава висок рейтинг. Както отбелязва „Ню Йорк Таймс“, решението на двамата кандидати да скъсат с традицията и да се срещат на събития, организирани от отделни телевизионни канали, е „огромен маркетингов успех [за Си Ен Ен – б.а.]… която тази година отбеляза най-ниските си рейтинги от 1991 г. насам със средни стойности под 100 000 зрители на възраст от 25 до 54 години на вечер“. Друга традиция, която дебатът в Атланта, Джорджия, ще наруши, е прекъсването за реклами: 90-минутното „шоу“ съдържа два рекламни блока от три-четири минути.
Три графики, които изобразяват нарастващите икономически неравенства в САЩ от 80-те години до наши дни. Източник: Urban Institute
САЩ, а и световната икономика се намират на особен кръстопът: идеологията на растежа безспорно е довела до подобряване на стандарта на живот през последните няколко столетия, но на високата цена на климатични промени, замърсяване на природата, опасно намаляване на важни ресурси като питейната вода, задълбочаващи се глобални (а вече и локални) неравенства, консолидация и монополи върху ресурси и цели сектори от страна на световни корпорации, които трудно подлежат на регулация и контрол чрез наличните демократични механизми като гласуването например.
Идеи като т.нар. degrowth movement (букв. „движение на свиването“) набират популярност, но все още не са масово разпространени. Дискусиите дали настоящите показатели за измерване на просперитета и стандарта на живот са адекватни спрямо съвремието, също зачестяват. Това обаче са сложни и широкообхватни проблеми с дългосрочни последствия. А избирателят иска решения тук и сега, по възможност без да мисли какви са причините настоящето да е такова, каквото е.
Шоуто на дебатите се очаква във време на рекордно ниско доверие в институциите от Втората световна война насам. Въпросът, който все по-често се задава не само от водещи експерти, но и се чува из американските барове, всекидневни и форуми, е „Докога можем да продължаваме така?“.
В следващ текст ще засегнем и други приоритети, като достъпа до аборт, конфликтите в Украйна и Газа, имиграцията и оръжията. Всички тези въпроси имат значение и за България не само защото САЩ е ключов международен партньор за страната ни, а и защото т.нар. културни войни се внасят у нас пряко от Съединените щати и оформят общественото мнение по всички въпроси от икономика до имиграция – сфери, в които все по-често споделяме не локални, а глобални проблеми.
The academic and the Linux real-time and scheduling community mourns the
premature death of Daniel Bristot de
Oliveira. Daniel died at the age of 37 on Monday, June 24, 2024.
Juri Lelli, Tommaso Cucinotta, Steve Rostedt, Kate Stewart, and Thomas
Gleixner have come together to share their thoughts on his life and what he
has left behind
Amazon Redshift is a fully managed, petabyte-scale data warehouse service in the cloud. You can start with just a few hundred gigabytes of data and scale to a petabyte or more. This enables you to use your data to acquire new insights for your business and customers.
The objective of a disaster recovery plan is to reduce disruption by enabling quick recovery in the event of a disaster that leads to system failure. Disaster recovery plans also allow organizations to make sure they meet all compliance requirements for regulatory purposes, providing a clear roadmap to recovery.
This post outlines proactive steps you can take to mitigate the risks associated with unexpected disruptions and make sure your organization is better prepared to respond and recover Amazon Redshift in the event of a disaster. With built-in features such as automated snapshots and cross-Region replication, you can enhance your disaster resilience with Amazon Redshift.
Disaster recovery planning
Any kind of disaster recovery planning has two key components:
Recovery Point Objective (RPO) – RPO is the maximum acceptable amount of time since the last data recovery point. This determines what is considered an acceptable loss of data between the last recovery point and the interruption of service.
Recovery Time Objective (RTO) – RTO is the maximum acceptable delay between the interruption of service and restoration of service. This determines what is considered an acceptable time window when service is unavailable.
To develop your disaster recovery plan, you should complete the following tasks:
Define your recovery objectives for downtime and data loss (RTO and RPO) for data and metadata. Make sure your business stakeholders are engaged in deciding appropriate goals.
Identify recovery strategies to meet the recovery objectives.
Define a fallback plan to return production to the original setup.
Test out the disaster recovery plan by simulating a failover event in a non-production environment.
Develop a communication plan to notify stakeholders of downtime and its impact to the business.
Develop a communication plan for progress updates, and recovery and availability.
Document the entire disaster recovery process.
Disaster recovery strategies
Amazon Redshift is a cloud-based data warehouse that supports many recovery capabilities out of the box to address unforeseen outages and minimize downtime.
Amazon Redshift RA3 instance types and Redshift serverless store their data in Redshift Managed Storage (RMS), which is backed by Amazon Simple Storage Service (Amazon S3), which is highly available and durable by default.
In the following sections, we discuss the various failure modes and associated recovery strategies.
Using backups
Backing up data is an important part of data management. Backups protect against human error, hardware failure, virus attacks, power outages, and natural disasters.
Amazon Redshift supports two kinds of snapshots: automatic and manual, which can be used to recover data. Snapshots are point-in-time backups of the Redshift data warehouse. Amazon Redshift stores these snapshots internally with RMS by using an encrypted Secure Sockets Layer (SSL) connection.
Redshift provisioned clusters offer automated snapshots that are taken automatically with a default retention of 1 day, which can be extended for up to 35 days. These snapshots are taken every 5 GB data change per node or every 8 hours, and the minimum time interval between two snapshots is 15 minutes. The data change must be greater than the total data ingested by the cluster (5 GB times the number of nodes). You can also set a custom snapshot schedule with frequencies between 1–24 hours. You can use the AWS Management Console or ModifyCluster API to manage the period of time your automated backups are retained by modifying the RetentionPeriod parameter. If you want to turn off automated backups altogether, you can set up the retention period to 0 (not recommended). For additional details, refer to Automated snapshots.
Amazon Redshift Serverless automatically creates recovery points approximately every 30 minutes. These recovery points have a default retention of 24 hours, after which they get automatically deleted. You do have the option to convert a recovery point into a snapshot if you want to retain it longer than 24 hours.
Both Amazon Redshift provisioned and serverless clusters offer manual snapshots that can be taken on-demand and be retained indefinitely. Manual snapshots allow you to retain your snapshots longer than automated snapshots to meet your compliance needs. Manual snapshots accrue storage charges, so it’s important that you delete them when you no longer need them. For additional details, refer to Manual snapshots.
Amazon Redshift integrates with AWS Backup to help you centralize and automate data protection across all your AWS services, in the cloud, and on premises. With AWS Backup for Amazon Redshift, you can configure data protection policies and monitor activity for different Redshift provisioned clusters in one place. You can create and store manual snapshots for Redshift provisioned clusters. This lets you automate and consolidate backup tasks that you had to do separately before, without any manual processes. To learn more about setting up AWS Backup for Amazon Redshift, refer to Amazon Redshift backups. As of this writing, AWS Backup does not integrate with Redshift Serverless.
Node failure
A Redshift data warehouse is a collection of computing resources called nodes. Amazon Redshift will automatically detect and replace a failed node in your data warehouse cluster. Amazon Redshift makes your replacement node available immediately and loads your most frequently accessed data from Amazon S3 first to allow you to resume querying your data as quickly as possible.
If this is a single-node cluster (which is not recommended for customer production use), there is only one copy of the data in the cluster. When it’s down, AWS needs to restore the cluster from the most recent snapshot on Amazon S3, and that becomes your RPO.
We recommend using at least two nodes for production.
Cluster failure
Each cluster has a leader node and one or more compute nodes. In the event of a cluster failure, you must restore the cluster from a snapshot. Snapshots are point-in-time backups of a cluster. A snapshot contains data from all databases that are running on your cluster. It also contains information about your cluster, including the number of nodes, node type, and admin user name. If you restore your cluster from a snapshot, Amazon Redshift uses the cluster information to create a new cluster. Then it restores all the databases from the snapshot data. Note that the new cluster is available before all of the data is loaded, so you can begin querying the new cluster in minutes. The cluster is restored in the same AWS Region and a random, system-chosen Availability Zone, unless you specify another Availability Zone in your request.
Availability Zone failure
A Region is a physical location around the world where data centers are located. An Availability Zone is one or more discrete data centers with redundant power, networking, and connectivity in a Region. Availability Zones enable you to operate production applications and databases that are more highly available, fault tolerant, and scalable than would be possible from a single data center. All Availability Zones in a Region are interconnected with high-bandwidth, low-latency networking, over fully redundant, dedicated metro fiber providing high-throughput, low-latency networking between Availability Zones.
To recover from Availability Zone failures, you can use one of the following approaches:
Relocation capabilities (active-passive) – If your Redshift data warehouse is a single-AZ deployment and the cluster’s Availability Zone becomes unavailable, then Amazon Redshift will automatically move your cluster to another Availability Zone without any data loss or application changes. To activate this, you must enable cluster relocation for your provisioned cluster through configuration settings, which is automatically enabled for Redshift Serverless. Cluster relocation is free of cost, but it is a best-effort approach subject to resource availability in the Availability Zone being recovered in, and RTO can be impacted by other issues related to starting up a new cluster. This can result in recovery times between 10–60 minutes. To learn more about configuring Amazon Redshift relocation capabilities, refer to Build a resilient Amazon Redshift architecture with automatic recovery enabled.
Amazon Redshift Multi-AZ (active-active) – A Multi-AZ deployment allows you to run your data warehouse in multiple Availability Zones simultaneously and continue operating in unforeseen failure scenarios. No application changes are required to maintain business continuity because the Multi-AZ deployment is managed as a single data warehouse with one endpoint. Multi-AZ deployments reduce recovery time by guaranteeing capacity to automatically recover and are intended for customers with mission-critical analytics applications that require the highest levels of availability and resiliency to Availability Zone failures. This also allows you to implement a solution that is more compliant with the recommendations of the Reliability Pillar of the AWS Well-Architected Framework. Our pre-launch tests found that the RTO with Amazon Redshift Multi-AZ deployments is under 60 seconds or less in the unlikely case of an Availability Zone failure. To learn more about configuring Multi-AZ, refer to Enable Multi-AZ deployments for your Amazon Redshift data warehouse. As of writing, Redshift Serverless currently does not support Multi-AZ.
Region failure
Amazon Redshift currently supports single-Region deployments for clusters. However, you have several options to help with disaster recovery or accessing data across multi-Region scenarios.
Use a cross-Region snapshot
You can configure Amazon Redshift to copy snapshots for a cluster to another Region. To configure cross-Region snapshot copy, you need to enable this copy feature for each data warehouse (serverless and provisioned) and configure where to copy snapshots and how long to keep copied automated or manual snapshots in the destination Region. When cross-Region copy is enabled for a data warehouse, all new manual and automated snapshots are copied to the specified Region. In the event of a Region failure, you can restore your Redshift data warehouse in a new Region using the latest cross-Region snapshot.
The following diagram illustrates this architecture. For more information about how to enable cross-Region snapshots, refer to the following:
A custom domain name is easier to remember and use than the default endpoint URL provided by Amazon Redshift. With CNAME, you can quickly route traffic to a new cluster or workgroup created from snapshot in a failover situation. When a disaster happens, connections can be rerouted centrally with minimal disruption, without clients having to change their configuration.
For high availability, you should have a warm-standby cluster or workgroup available that regularly receives restored data from the primary cluster. This backup data warehouse could be in another Availability Zone or in a separate Region. You can redirect clients to the secondary Redshift cluster by setting up a custom domain name in the unlikely scenario of an entire Region failure.
In the following sections, we discuss how to use a custom domain name to handle Region failure in Amazon Redshift. Make sure the following prerequisites are met:
You need a registered domain name. You can use Amazon Route 53 or a third-party domain registrar to register a domain.
Take note of your Redshift endpoint. You can locate the endpoint by navigating to your Redshift workgroup or provisioned cluster name on the Amazon Redshift console.
Set up a custom domain with Amazon Redshift in the primary Region
In the hosted zone that Route 53 created when you registered the domain, create records to tell Route 53 how you want to route traffic to Redshift endpoint by completing the following steps:
On the Route 53 console, choose Hosted zones in the navigation pane.
Choose your hosted zone.
On the Records tab, choose Create record.
For Record name, enter your preferred subdomain name.
For Record type, choose CNAME.
For Value, enter the Redshift endpoint name. Make sure to provide the value by removing the colon (:), port, and database. For example, redshift-provisioned.eabc123.us-east-2.redshift.amazonaws.com.
You can now connect to your cluster using the custom domain name. The JDBC URL will be similar to jdbc:redshift://prefix.rootdomain.com:5439/dev?sslmode=verify-full, where prefix.rootdomain.com is your custom domain name and dev is the default database. Use your preferred editor to connect to this URL using your user name and password.
Steps to handle a Regional failure
In the unlikely situation of a Regional failure, complete the following steps:
Turn on cluster relocation for your Redshift cluster in the secondary Region. Use the AWS CLI to turn on relocation for a Redshift provisioned cluster.
Use the CNAME record name from the Route 53 hosted zone setup to create a custom domain in the newly created Redshift cluster or workgroup.
Take note of the Redshift endpoint’s newly created Redshift cluster or workgroup.
Next, you need to update the Redshift endpoint in Route 53 for achieve seamless connectivity.
On the Route 53 console, choose Hosted zones in the navigation pane.
Choose your hosted zone.
On the Record tab, select the CNAME record you created.
Under Record details, choose Edit record.
Change the value to the newly created Redshift endpoint. Make sure to provide the value by removing the colon (:), port, and database. For example, redshift-provisioned.eabc567.us-west-2.redshift.amazonaws.com.
Choose Save.
Now when you connect to your custom domain name using the same JDBC URL from your application, you should be connected to your new cluster in your secondary Region.
Use active-active configuration
For business-critical applications that require high availability, you can set up an active-active configuration at the Region level. There are many ways to make sure all writes occur to all clusters; one way is to keep the data in sync between the two clusters by ingesting data concurrently into the primary and secondary cluster. You can also use Amazon Kinesis to sync the data between two clusters. For more details, see Building Multi-AZ or Multi-Region Amazon Redshift Clusters.
Additional considerations
In this section, we discuss additional considerations for your disaster recovery strategy.
Amazon Redshift Spectrum
Amazon Redshift Spectrum is a feature of Amazon Redshift that allows you to run SQL queries against exabytes of data stored in Amazon S3. With Redshift Spectrum, you don’t have to load or extract the data from Amazon S3 into Amazon Redshift before querying.
If you’re using external tables using Redshift Spectrum, you need to make sure it is configured and accessible on your secondary failover cluster.
With Amazon Redshift data sharing, you can securely share read access to live data across Redshift clusters, workgroups, AWS accounts, and Regions without manually moving or copying the data.
If you’re using cross-Region data sharing and one of the Regions has an outage, you need to have a business continuity plan to fail over your producer and consumer clusters to minimize the disruption.
In the event of an outage affecting the Region where the producer cluster is deployed, you can take the following steps to create a new producer cluster in another Region using a cross-Region snapshot and by reconfiguring data sharing, allowing your system to continue operating:
Create a new Redshift cluster using the cross-Region snapshot. Make sure you have correct node type, node count, and security settings.
Identify the Redshift data shares that were previously configured for the original producer cluster.
Recreate these data shares on the new producer cluster in the target Region.
Update the data share configurations in the consumer cluster to point to the newly created producer cluster.
Confirm that the necessary permissions and access controls are in place for the data shares in the consumer cluster.
Verify that the new producer cluster is operational and the consumer cluster is able to access the shared data.
In the event of an outage in the Region where the consumer cluster is deployed, you will need to create a new consumer cluster in a different Region. This makes sure all applications that are connecting to the consumer cluster continue to function as expected, with proper access.
The steps to accomplish this are as follows:
Identify an alternate Region that is not affected by the outage.
Provision a new consumer cluster in the alternate Region.
Provide necessary access to data sharing objects.
Update the application configurations to point to the new consumer cluster.
Validate that all the applications are able to connect to the new consumer cluster and are functioning as expected.
For additional information on how to configure data sharing, refer to Sharing datashares.
Federated queries
With federated queries in Amazon Redshift, you can query and analyze data across operational databases, data warehouses, and data lakes. If you’re using federated queries, you need to set up federated queries from the failover cluster as well to prevent any application failure.
Summary
In this post, we discussed various failure scenarios and recovery strategies associated with Amazon Redshift. Disaster recovery solutions make restoring your data and workloads seamless so you can get business operations back online quickly after a catastrophic event.
As an administrator, you can now work on defining your Amazon Redshift disaster recovery strategy and implement it to minimize business disruptions. You should develop a comprehensive plan that includes:
Identifying critical Redshift resources and data
Establishing backup and recovery procedures
Defining failover and failback processes
Enforcing data integrity and consistency
Implementing disaster recovery testing and drills
Try out these strategies for yourself, and leave any questions and feedback in the comments section.
About the authors
Nita Shah is a Senior Analytics Specialist Solutions Architect at AWS based out of New York. She has been building data warehouse solutions for over 20 years and specializes in Amazon Redshift. She is focused on helping customers design and build enterprise-scale well-architected analytics and decision support platforms.
Poulomi Dasgupta is a Senior Analytics Solutions Architect with AWS. She is passionate about helping customers build cloud-based analytics solutions to solve their business problems. Outside of work, she likes travelling and spending time with her family.
Ranjan Burman is an Analytics Specialist Solutions Architect at AWS. He specializes in Amazon Redshift and helps customers build scalable analytical solutions. He has more than 16 years of experience in different database and data warehousing technologies. He is passionate about automating and solving customer problems with cloud solutions.
Jason Pedreza is a Senior Redshift Specialist Solutions Architect at AWS with data warehousing experience handling petabytes of data. Prior to AWS, he built data warehouse solutions at Amazon.com and Amazon Devices. He specializes in Amazon Redshift and helps customers build scalable analytic solutions.
Agasthi Kothurkar is an AWS Solutions Architect, and is based in Boston. Agasthi works with enterprise customers as they transform their business by adopting the Cloud. Prior to joining AWS, he worked with leading IT consulting organizations on customers engagements spanning Cloud Architecture, Enterprise Architecture, IT Strategy, and Transformation. He is passionate about applying Cloud technologies to resolve complex real world business problems.
Generative artificial intelligence (AI) has gained a lot of traction in 2024, especially around large language models (LLMs) that enable intelligent chatbot solutions. Amazon Bedrock is a fully managed service that offers a choice of high-performing foundation models (FMs) from leading AI companies such as AI21 Labs, Anthropic, Cohere, Meta, Mistral AI, Stability AI, and Amazon through a single API, along with a broad set of capabilities to help you build generative AI applications with security, privacy, and responsible AI. Use cases around generative AI are vast and go well beyond chatbot applications; for instance, generative AI can be used for analysis of input data such as sentiment analysis of reviews.
Most businesses generate data continuously in real-time. Internet of Things (IoT) sensor data, application log data from your applications, or clickstream data generated by users of your website are only some examples of continuously generated data. In many situations, the ability to process this data quickly (in real-time or near real-time) helps businesses increase the value of insights they get from their data.
One option to process data in real-time is using stream processing frameworks such as Apache Flink. Flink is a framework and distributed processing engine for processing data streams. AWS provides a fully managed service for Apache Flink through Amazon Managed Service for Apache Flink, which enables you to build and deploy sophisticated streaming applications without setting up infrastructure and managing resources.
Data streaming enables generative AI to take advantage of real-time data and provide businesses with rapid insights. This post looks at how to integrate generative AI capabilities when implementing a streaming architecture on AWS using managed services such as Managed Service for Apache Flink and Amazon Kinesis Data Streams for processing streaming data and Amazon Bedrock to utilize generative AI capabilities. We focus on the use case of deriving review sentiment in real-time from customer reviews in online shops. We include a reference architecture and a step-by-step guide on infrastructure setup and sample code for implementing the solution with the AWS Cloud Development Kit (AWS CDK). You can find the code to try it out yourself on the GitHub repo.
Solution overview
The following diagram illustrates the solution architecture. The architecture diagram depicts the real-time streaming pipeline in the upper half and the details on how you gain access to the Amazon OpenSearch Service dashboard in the lower half.
The real-time streaming pipeline consists of a producer that is simulated by running a Python script locally that is sending reviews to a Kinesis Data Stream. The reviews are from the Large Movie Review Dataset and contain positive or negative sentiment. The next step is the ingestion to the Managed Service for Apache Flink application. From within Flink, we are asynchronously calling Amazon Bedrock (using Anthropic Claude 3 Haiku) to process the review data. The results are then ingested into an OpenSearch Service cluster for visualization with OpenSearch Dashboards. We directly call the PutRecords API of Kinesis Data Streams within the Python script for the sake of simplicity and to cost-effectively run this example. You should consider using an Amazon API Gateway REST API as a proxy in front of Kinesis Data Streams when using a similar architecture in production, as described in Streaming Data Solution for Amazon Kinesis.
To gain access to the OpenSearch dashboard, we need to use a bastion host that is deployed in the same private subnet within your virtual private cloud (VPC) as your OpenSearch Service cluster. To connect with the bastion host, we use Session Manager, a capability of Amazon Systems Manager, which allows us to connect to our bastion host securely without having to open inbound ports. To access it, we use Session Manager to port forward the OpenSearch dashboard to our localhost.
The walkthrough consists of the following high-level steps:
Create the Flink application by building the JAR file.
Deploy the AWS CDK stack.
Set up and connect to OpenSearch Dashboards.
Set up the streaming producer.
Prerequisites
For this walkthrough, you should have the following prerequisites:
Model access to Anthropic’s Claude model on Amazon Bedrock. For instructions, refer to Add model access.
The dataset used is the Large Movie Review Dataset from the following paper: Andrew L. Maas, Raymond E. Daly, Peter T. Pham, Dan Huang, Andrew Y. Ng, and Christopher Potts. (2011). Learning Word Vectors for Sentiment Analysis.The 49th Annual Meeting of the Association for Computational Linguistics (ACL 2011).
Implementation details
This section focuses on the Flink application code of this solution. You can find the code on GitHub. The StreamingJob.java file inside the flink-async-bedrock directory file serves as entry point to the application. The application uses the FlinkKinesisConsumer, which is a connector for reading streaming data from a Kinesis Data Stream. It applies a map transformation to convert each input string into an instance of Review class object, resulting in DataStream<Review> to ease processing.
The Flink application uses the helper class AsyncDataStream defined in the StreamingJob.java file to incorporate an asynchronous, external operation into Flink. More specifically, the following code creates an asynchronous data stream by applying the AsyncBedrockRequest function to each element in the inputReviewStream. The application uses unorderedWait to increase throughput and reduce idle time because event ordering is not required. The timeout is set to 25,000 milliseconds to give the Amazon Bedrock API enough time to process long reviews. The maximum concurrency or capacity is limited to 1,000 requests at a time. See the following code:
DataStream<ProcessedReview> processedReviewStream = AsyncDataStream.unorderedWait(inputReviewStream, new AsyncBedrockRequest(applicationProperties), 25000, TimeUnit.MILLISECONDS, 1000).uid("processedReviewStream");
The Flink application initiates asynchronous calls to the Amazon Bedrock API, invoking the Anthropic Claude 3 Haiku foundation model for each incoming event. We use Anthropic Claude 3 Haiku on Amazon Bedrock because it is Anthropic’s fastest and most compact model for near-instant responsiveness. The following code snippet is part of the AsyncBedrockRequest.java file and illustrates how we set up the required configuration to call the Anthropic’s Claude Messages API to invoke the model:
The application uses advanced prompt engineering techniques to guide the generative AI model’s responses and provide consistent responses. The following prompt is designed to extract a summary as well as a sentiment from a single review:
String systemPrompt =
     "Summarize the review within the <review> tags
     into a single and concise sentence alongside the sentiment
     that is either positive or negative. Return a valid JSON object with
     following keys: summary, sentiment.
     <example> {\\\"summary\\\": \\\"The reviewer strongly dislikes the movie,
     finding it unrealistic, preachy, and extremely boring to watch.\\\",
     \\\"sentiment\\\": \\\"negative\\\"}
     </example>";
The prompt instructs the Anthropic Claude model to return the extracted sentiment and summary in JSON format. To maintain consistent and well-structured output by the generative AI model, the prompt uses various prompt engineering techniques to improve the output. For example, the prompt uses XML tags to provide a clearer structure for Anthropic Claude. Moreover, the prompt contains an example to enhance Anthropic Claude’s performance and guide it to produce the desired output. In addition, the prompt pre-fills Anthropic Claude’s response by pre-filling the Assistant message. This technique helps provide a consistent output format. See the following code:
JSONObject assistant_message = new JSONObject()
    .put("role", "assistant")
    .put("content", "{");
Build the Flink application
The first step is to download the repository and build the JAR file of the Flink application. Complete the following steps:
Move to the correct directory inside the downloaded repository and build the Flink application:
cd flink-async-bedrock && mvn clean package
Maven will compile the Java source code and package it in a distributable JAR format in the directory flink-async-bedrock/target/ named flink-async-bedrock-0.1.jar. After you deploy your AWS CDK stack, the JAR file will be uploaded to Amazon Simple Storage Service (Amazon S3) to create your Managed Service for Apache Flink application.
Deploy the AWS CDK stack
After you build the Flink application, you can deploy your AWS CDK stack and create the required resources:
Move to the correct directory cdk and deploy the stack:
cd cdk && npm install & cdk deploy
This will create the required resources in your AWS account, including the Managed Service for Apache Flink application, Kinesis Data Stream, OpenSearch Service cluster, and bastion host to quickly connect to OpenSearch Dashboards, deployed in a private subnet within your VPC.
Take note of the output values. The output will look similar to the following:
Next, you can set up and connect to OpenSearch Dashboards. This is where the Flink application will write the extracted sentiment as well as the summary from the processed review stream. Complete the following steps:
Run the following command to establish connection to OpenSearch from your local workspace in a separate terminal window. The command can be found as output named accessOpenSearchClusterOutput.
After the session is established, you can open your browser and navigate to https://localhost:8157/_dashboards. Your browser might consider the URL not secure. You can ignore this warning.
Choose Dashboards Management under Management in the navigation pane.
Choose Saved objects in the sidebar.
Import export.ndjson, which can be found in the resources folder within the downloaded repository.
After you import the saved objects, you can navigate to Dashboards under My Dashboard in the navigation pane.
At the moment, the dashboard appears blank because you haven’t uploaded any review data to OpenSearch yet.
Set up the streaming producer
Finally, you can set up the producer that will be streaming review data to the Kinesis Data Stream and ultimately to the OpenSearch Dashboards. The Large Movie Review Dataset was originally published in 2011 in the paper “Learning Word Vectors for Sentiment Analysis” by Andrew L. Maas, Raymond E. Daly, Peter T. Pham, Dan Huang, Andrew Y. Ng, and Christopher Potts. Complete the following steps:
After the download is complete, extract the .tar.gz file to retrieve the folder named aclImdb 3 or similar that contains the review data. Rename the review data folder to aclImdb.
Move the extracted dataset to data/ inside the repository that you previously downloaded.
Your repository should look like the following screenshot.
Modify the DATA_DIR path in producer/producer.py if the review data is named differently.
Move to the producer directory using the following command:
cd producer
Install the required dependencies and start generating the data:
The OpenSearch dashboard should be populated after you start generating streaming data and writing it to the Kinesis Data Stream. Refresh the dashboard to view the latest data. The dashboard shows the total number of processed reviews, the sentiment distribution of the processed reviews in a pie chart, and the summary and sentiment for the latest reviews that have been processed.
When you have a closer look at the Flink application, you will notice that the application marks the sentiment field with the value error whenever there is an error with the asynchronous call made by Flink to the Amazon Bedrock API. The Flink application simply filters the correctly processed reviews and writes them to the OpenSearch dashboard.
For robust error handling, you should write any incorrectly processed reviews to a separate output stream and not discard them completely. This separation allows you to handle failed reviews differently than successful ones for simpler reprocessing, analysis, and troubleshooting.
Clean up
When you’re done with the resources you created, complete the following steps:
Delete the Python producer using Ctrl/Command + C.
Destroy your AWS CDK stack by returning to the root folder and running the following command in your terminal:
cd cdk && cdk destroy
When asked to confirm the deletion of the stack, enter yes.
Conclusion
In this post, you learned how to incorporate generative AI capabilities in your streaming architecture using Amazon Bedrock and Managed Service for Apache Flink using asynchronous requests. We also gave guidance on prompt engineering to derive the sentiment from text data using generative AI. You can build this architecture by deploying the sample code from the GitHub repository.
Felix John is a Solutions Architect and data streaming expert at AWS, based in Germany. He focuses on supporting small and medium businesses on their cloud journey. Outside of his professional life, Felix enjoys playing Floorball and hiking in the mountains.
Michelle Mei-Li Pfister is a Solutions Architect at AWS. She is supporting customers in retail and consumer packaged goods (CPG) industry on their cloud journey. She is passionate about topics around data and machine learning.
The Free Software Foundation (FSF) has announced
the addition of three new members to its board: John Gilmore,
Christina Haralanova, and Maria Chiara Pievatolo. This is part of FSF
governance changes announced
in January 2023. The next step is a review of current board
members:
These three new members of the FSF’s board of directors are the first
to be appointed since 2020, when Odile Bénassy joined. Given the
importance of the FSF to the free software movement, and the
importance of its board to ensure preservation of the software freedom
definition, the board has not taken its task lightly. Next, the FSF
will evaluate current board members with the FSF’s associate members
in August, after which the voting
members will review the feedback
received and decide if each current board member should remain.
More information on the process, and a short biography of each new
board member, is available in the full announcement.
The following Rapid7 analysts contributed to this research: Leo Gutierrez, Tyler McGraw, Sarah Lee, and Thomas Elkins.
Executive Summary
On Tuesday, June 18th, 2024, Rapid7 initiated an investigation into suspicious activity in a customer environment. Our investigation identified that the suspicious behavior was emanating from the installation of Notezilla, a program that allows for the creation of sticky notes on a Windows desktop. Installers for Notezilla, along with tools called RecentX and Copywhiz, are distributed by the India-based company Conceptworld at the official domain conceptworld[.]com. After analyzing the installation packages for all three programs, Rapid7 discovered that the installers had been trojanized to execute information-stealing malware that has the capability to download and execute additional payloads.
Disclosure
On Monday, June 24th, 2024, Rapid7 contacted Conceptworld to disclose the backdoored installers being hosted on conceptworld[.]com in accordance with Rapid7’s vulnerability disclosure policy. Within 12 hours, Conceptworld confirmed and remediated the issue by removing the malicious installers from conceptworld[.]com and replacing them with legitimate, signed copies. Rapid7 is grateful to Conceptworld for their prompt action on this issue.
Overview
Conceptworld is an India-based company offering three different software products: Notezilla, which allows users to create sticky notes on a Windows desktop; RecentX, which stores recently used files/applications/clipboard data; and Copywhiz, which improves file copying and backup operations. A free trial download is available on the official conceptworld[.]com site for each software package.
The installation packages being served by conceptworld[.]com at the time of investigation, however, executed malware alongside the legitimate installer, were not signed, and did not match the file size stated on the download page. The differences in the file sizes are due to the malware and its dependencies, which increases the size of the compromised installation packages.
The malware Rapid7 observed contains the functionality to steal browser credentials and crypto currency wallet information, log clipboard contents and keystrokes, and download and execute additional payloads. After infecting a system, the malware persists via a scheduled task that executes the primary payload every three hours.
Based on file submissions to VirusTotal, the malicious copies of the installers have existed since early June of 2024. The malware payloads delivered by the trojanized installers, however, seem to belong to a nameless malware family that has been in distribution since at least January of 2024. Rapid7 internally refers to this malware family as dllFake because of the naming scheme used for several of the malware payloads.
Malicious installer name
VirusTotal First Submission
NotezillaSetup.exe
2024-06-10 06:43:34 UTC
RecentXSetup.exe
2024-06-07 21:38:11 UTC
CopywhizSetup.exe
2024-06-08 07:25:17 UTC
Technical analysis
To take a deeper look at the malware payloads, we will analyze the malicious installer that was served for Notezilla.
Initial Access
Rapid7 determined that trojanized installers for the 32-bit and 64-bit versions of Notezilla, Copywhiz, and RecentX were, at the time of investigation, being served from the official website conceptworld[.]com. Any users searching for this software via a popular search engine at the time were most likely to find the official domain as the first result, which would then have directed them to download the malware.
Execution
The installer served by conceptworld[.]com for Notezilla at the time of investigation was NotezillaSetup.exe, which, based on static analysis, is packed using software called Smart Install Maker(5.04).
Figure 1. Software Properties of NotezillaSetup.exe.
Using the sim_unpacker plugin for the tool UniExtract2, we were able to unpack and acquire most of the contents of the installation package, such as the embedded files and configuration information. The configuration file contains references to the legitimate software installer for Notezilla, which is dropped into %TEMP% during execution, and multiple files that are dropped into the installation directory (i.e., staging folder) %LOCALAPPDATA%\Microsoft\WindowsApps\ during execution.
Installer Files
curl.exe
7z.exe
dllBus.bat
dllBus32.exe
dllCrt.bat
dllCrt.xml
dllCrt32.exe
dll_apps.txt
dll_srv.txt
dll_updt.txt
NotezillaSetup.exe
Figure 2. Output from Using the sim-unpacker tool.
Figure 3. Contents of installer.config.
Once executed, NotezillaSetup.exe will then execute the file dllCrt32.exe from the staging directory %LOCALAPPDATA%\Microsoft\WindowsApps\ via a WINAPI call to ShellExecuteA with the verb open. A second call is then made to ShellExecuteA to execute the file NotezillaSetup.exe, a copy of the legitimate installer, from %TEMP%. As a result, the only thing seen by the end user after initial execution is the installation window pop-up for the legitimate installer, prompting the user to proceed with the installation process for Notezilla.
Figure 4. Typical Process Tree for Initial Execution of the Trojanized Installer.
Figure 5. The User’s View after the Infection has Already Begun in the Background.
The file dllCrt32.exe is a relatively small (~10KB) program that only serves as a wrapper to call CreateProcessA to execute the file dllCrt.bat.
Figure 6. The Contents of dllCrt.bat.
The batch file dllCrt.bat will then create a hidden scheduled task named Check dllHourly32 using schtasks.exe and an XML file that was previously dropped into the staging directory at %LOCALAPPDATA%\Microsoft\WindowsApps\dllCrt.xml. The scheduled task Check dllHourly32 will then execute the file %LOCALAPPDATA%\Microsoft\WindowsApps\dllBus32.exe every three hours after being initially created, which means that the primary malware payload will not be executed until at least three hours after the user originally executed the trojanized installer.
Figure 7. Command Line Assembly within dllBus32.exe.
When dllBus32.exe is executed, it also serves as a small wrapper for calling CreateProcessA, though it initially retrieves several important command line parameters. First, a call to the CRT library function sprintf concatenates a hard-coded IPv4 address. Then, a second call to sprintf concatenates the assembled IPv4 address with several other arguments to be passed to the batch file dllBus.bat. Finally, CreateProcessA is called with the fully assembled command line.
Figure 8. The Initial Lines of dllBus.bat.
The command line arguments passed to dllBus.bat via dllBus32.exe contain an IPv4 address, an SFTP port, a password for ZIP archive payloads, two sets of SFTP credentials, and the staging directory where the majority of the malware’s files are located.
Argument #
Purpose
Value
Notes
1
C2 IPv4 Address
212.70.149[.]210
Stored within dllBus32.exe.
2
SFTP Port
2265
Used for all curl requests regardless of the IPv4 address.
3
ZIP password
MnX!8fsGt0@
Used to decrypt/extract downloaded archives.
4
SFTP Username
phn_sys
The SFTP credentials used for uploading stolen data.
5
SFTP Password
Password for phn_sys.
6
SFTP Username
phn_prj
The SFTP credentials used for downloading payloads.
7
SFTP Password
Password for phn_prj
The batch file dllBus.bat contains functionality to facilitate the theft of information from Google Chrome, Mozilla Firefox, and multiple cryptocurrency wallets. The copy of curl.exe dropped by the installer is also used to connect to a list of command-and-control (C2) addresses hosting SFTP servers. The curl commands are used to download an updated list of C2 addresses, stored as plaintext within the file dll_srv.txt, and to download and execute additional payloads saved within encrypted ZIP archives named Updt.zip, Apps.zip, and BB.zip. The batch script will also attempt to compress all files on the infected system that have specific file extensions and exist in directories that are not on a hardcoded blacklist (for exfiltration). All stolen data is ultimately compressed using 7z.exe and uploaded directly to the selected C2 SFTP server using curl.
The payloads Apps.zip and Updt.zip both contain executables created using PyInstaller, which means the original Python script used to create the executables can be recovered trivially using a publicly available extractor. The payload dllChrome32.exe, contained within Updt.zip, is used to facilitate theft of credentials from Google Chrome’s database that are then saved into the file %TEMP%\chrm.txt with the format: URL, Username, Password.
Figure 9. Primary Functionality of dllChrome32.exe.
The payloads dllTemp32.exe and dllCache32.exe stored within Apps.zip contain a clipboard stealer and a keylogger, where the results are saved to the files cl.txt and kl.txt, respectively, within the staging directory at %LOCALAPPDATA%\Microsoft\WindowsApps\.
Figure 10. All Data Copied to the Clipboard is Dumped to cl.txt when dllTemp32.exe is Running.
Figure 11. dllCache32.exe Logs Keystrokes to kl.txt when Running.
Rapid7 did not observe any of the identified SFTP servers hosting the third payload, BB.zip, at the time of writing, although the contents of dllBus.bat indicate that it contains the executables srvBus32.exe and srvCrt32.exe, which serve an unknown function.
Mitigation Guidance
Rapid7 recommends verifying the file integrity of freely available software. Check that the file hash and properties of the downloaded file(s) match those provided by the official distributor and/or that they contain a valid and relevant signature. The malicious installers observed in this case are unsigned and have a file size that is inconsistent with copies of the legitimate installer, even as noted on the official download page.
If an installer for Notezilla, RecentX, or Copywhiz has been executed on a system within the last month, Rapid7 recommends checking for signs of compromise due to the malicious installers detailed in this blog. The primary indicators of infection include the hidden scheduled task Check dllHourly32 and a persistent running instance of the Windows Command Prompt, cmd.exe, which makes outbound network connections via curl.exe.
If evidence of compromise is found, Rapid7 recommends re-imaging affected systems to a known good baseline to eradicate any changes made by the malware.
Rapid7 Customers
InsightIDR, Managed Detection and Response, and Managed Threat Complete customers have existing detection coverage through Rapid7’s expansive library of detection rules. Rapid7 recommends installing the Insight agent on all applicable hosts to ensure visibility into suspicious processes and proper detection coverage. Below is a non-exhaustive list of detections that are deployed and will alert on behavior related to this activity:
Detections
Persistence – SchTasks Creating A Task Pointed At Users Temp Or Roaming Directory
Attacker – Extraction Of 7zip Archive With Password
Suspicious Process – 7zip Executed From Users Directory
Suspicious Process – TaskKill Executed Successively In Short Time Period
Attacker Technique – Curl or Wget To Public IP Address With Non Standard Port
Amazon CodeCatalyst is a unified software development and delivery service. It enables software development teams to quickly and easily plan, develop, collaborate on, build, and deliver applications on Amazon Web Services (AWS), reducing friction throughout the development lifecycle.
The GitHub, GitLab.com, and Bitbucket Cloud repositories extension for CodeCatalyst simplifies managing your development workflow. The extension allows you to view and manage external repositories directly within CodeCatalyst. Additionally, you can store and manage workflow definition files alongside your code in external repositories while also creating, reading, updating, and deleting files in linked repositories from CodeCatalyst dev environments. The extension also triggers CodeCatalyst workflow runs automatically upon code pushes and when pull requests are opened, merged, or closed. Furthermore, it allows you to directly utilize source files from linked repositories and execute actions within CodeCatalyst workflows, eliminating the need to switch platforms and maximizing efficiency.
But there’s more: starting today, you can create a CodeCatalyst project in a GitHub, GitLab.com, or Bitbucket Cloud repository from a blueprint, you can add a blueprint to an existing code base in a repository on any of those three systems, and you can also create custom blueprints stored in your external repositories hosted on GitHub, GitLab.com, or Bitbucket Cloud.
CodeCatalyst blueprints help to speed up your developments. These pre-built templates provide a source repository, sample code, continuous integration and delivery (CI/CD) workflows, and integrated issue tracking to get you started quickly. Blueprints automatically update with best practices, keeping your code modern. IT leaders can create custom blueprints to standardize development for your team, specifying technology, access controls, deployment, and testing methods. And now, you can use blueprints even if your code resides in GitHub, GitLab.com, or Bitbucket Cloud.
Link your CodeCatalyst space with a git repository hosting service Getting started using any of these three source code repository providers is easy. As a CodeCatalyst space administrator, I select the space where I want to configure the extensions. Then, I select Settings, and in the Installed extensions section, I select Configure to link my CodeCatalyst space with my GitHub, GitLab.com, or Bitbucket Cloud account.
This is a one-time operation for each CodeCatalyst space, but you might want to connect your space to multiple source providers’ accounts.
When using GitHub, I also have to link my personal CodeCatalyst user to my GitHub user. Under my personal menu on the top right side of the screen, I select My settings. Then, I navigate down to the Personal connections section. I select Create and follow the instructions to authenticate on GitHub and link my two identities.
This is a one-time operation for each user in the CodeCatalyst space. This is only required when you’re using GitHub with blueprints.
Create a project from a blueprint and host it on GitHub, GitLab.com, and Bitbucket Cloud Let’s show you how to create a project in an external repository from a blueprint and later add other blueprints to this project. You can use any of the three git hosting providers supported by CodeCatalyst. In this demo, I chose to use GitHub.
Let’s imagine I want to create a new project to implement an API. I start from a blueprint that implements an API with Python and the AWS Serverless Application Model (AWS SAM). The blueprint also creates a CI workflow and an issue management system. I want my project code to be hosted on GitHub. It allows me to directly use source files from my repository in GitHub and execute actions within CodeCatalyst workflows, eliminating the need to switch platforms.
I start by selecting Create project on my CodeCatalyst space page. I select Start with a blueprint and select the CodeCatalyst blueprint or Space blueprint I want to use. Then, I select Next.
I enter a name for my project. I open the Advanced section, and I select GitHub as Repository provider and my GitHub account. You can configure additional connections to GitHub by selecting Connect a GitHub account.
The rest of the configuration depends on the selected blueprint. In this case, I chose the language version, the AWS account to deploy the project to, the name of the AWS Lambda function, and the name of the AWS CloudFormation stack.
After the project is created, I navigate to my GitHub account, and I can see that a new repository has been created. It contains the code and resources from the blueprint.
I can now add a blueprint to an existing project in an external source code repository. Now that my backend API project has been created, I want to add a web application to my project.
I navigate to the Blueprints section in the left-side menu, and I select the orange Add blueprint button on the top-right part of the screen.
I select the Single-page application blueprint and select Next.
On the next screen, I make sure to select my GitHub connection, as I did when I created the project. I also fill in the required information for this specific template. On the right side of the screen, I review the proposed changes.
When CodeCatalyst finishes installing the new blueprint, I can see a second repository on GitHub.
Single or multiple repository strategies When organizing code, you can choose between a single large repository, like a toolbox overflowing with everything, or splitting it into smaller, specialized ones for better organization. Single repositories simplify dependency management for tightly linked projects but can become messy at scale. Multiple repositories offer cleaner organization and improved security but require planning to manage dependencies between separate projects.
In the example I showed before, the blueprint I selected proposed to apply the second blueprint as a separate repository in GitHub. Depending on the blueprint you selected, the blueprint may propose that you create a separate repository or merge the new code in an existing repository. In the latter case, the blueprint will submit a pull request for you to merge into your repository.
Region and availability This new GitHub integration is available at no additional cost in the two AWS Regions where Amazon CodeCatalyst is available, US West (Oregon) and Europe (Ireland) at the time of publication.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.


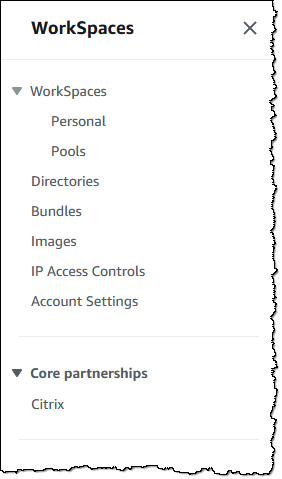
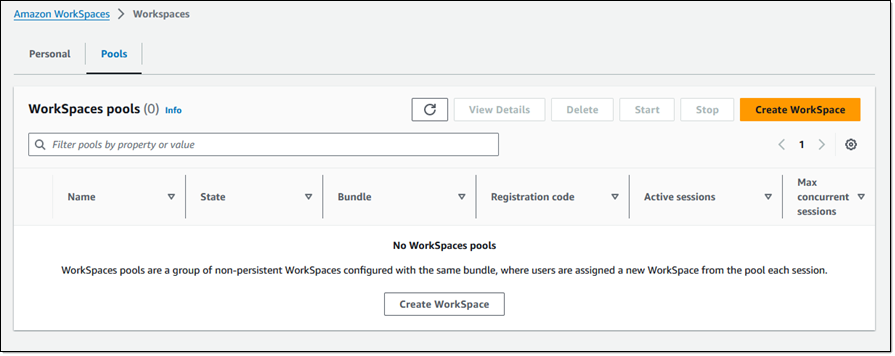
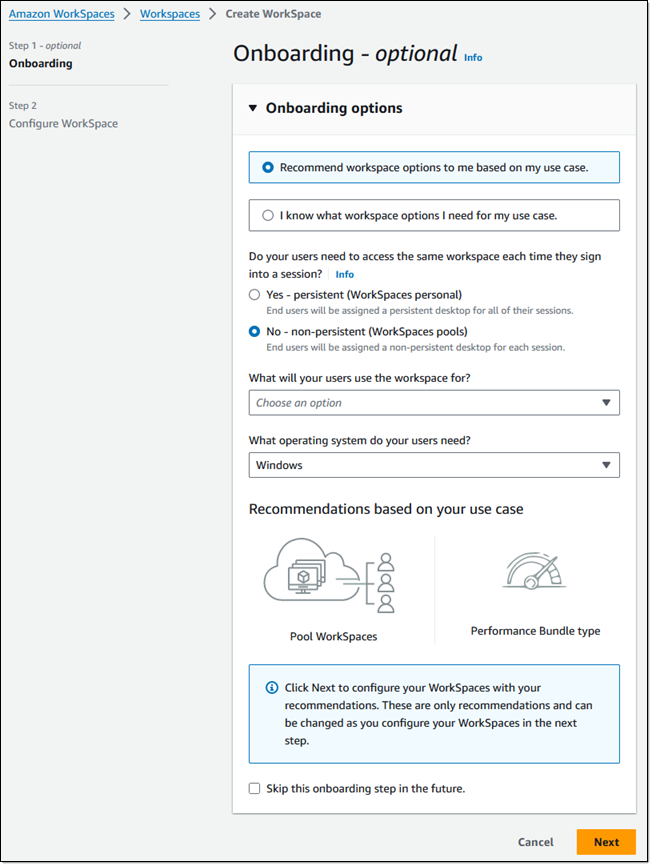
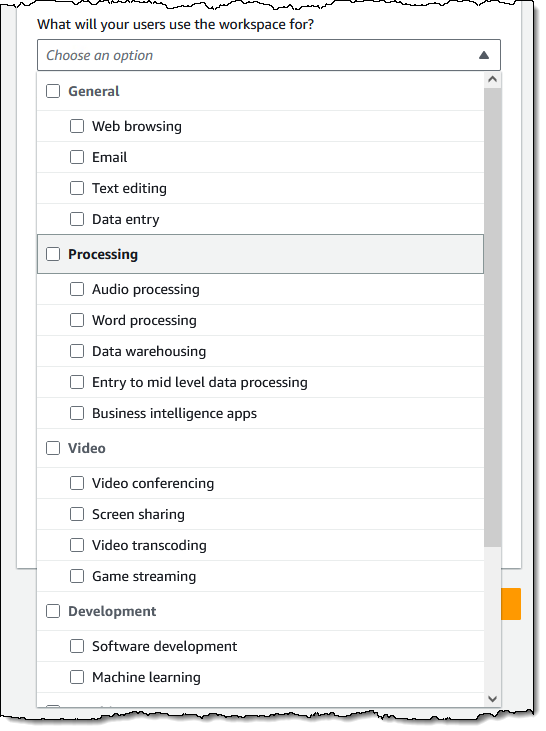
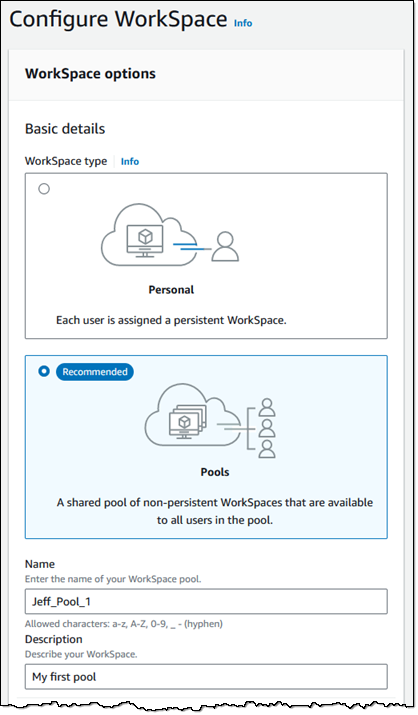
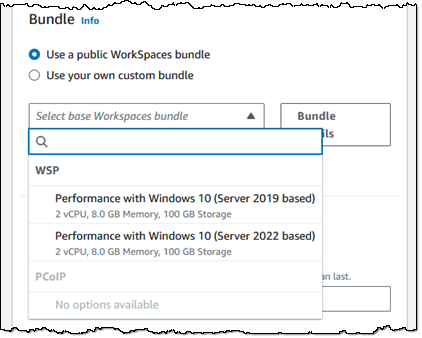
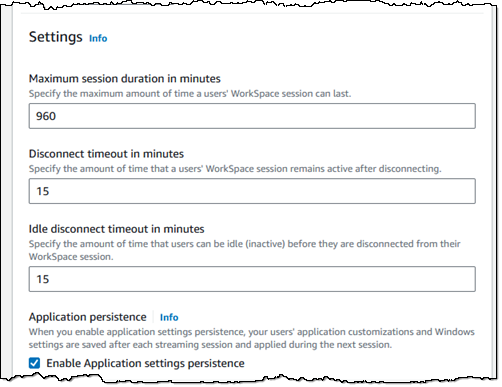
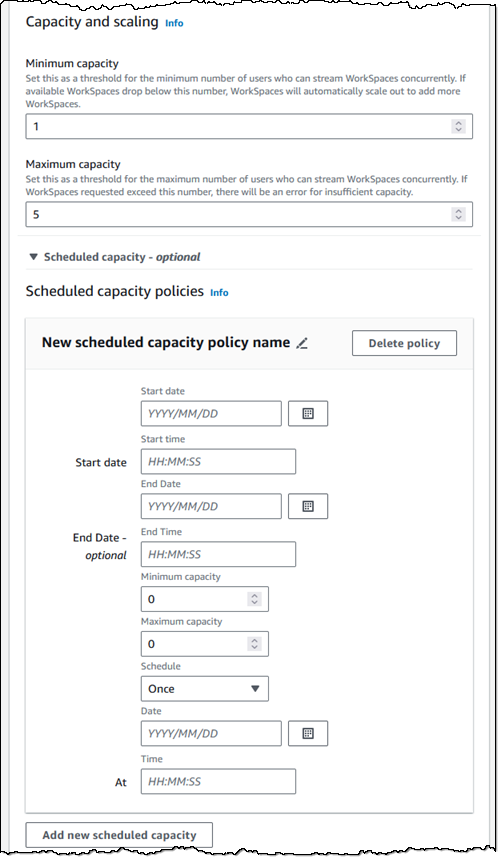
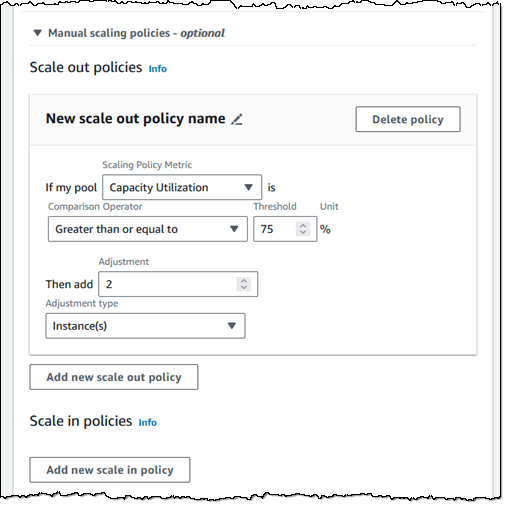
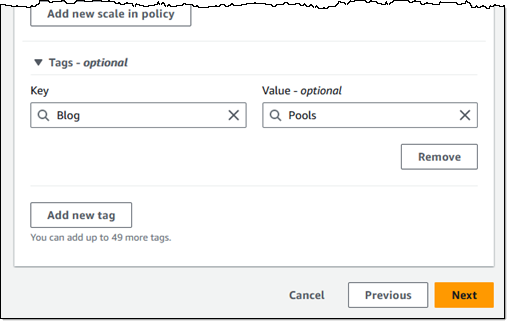


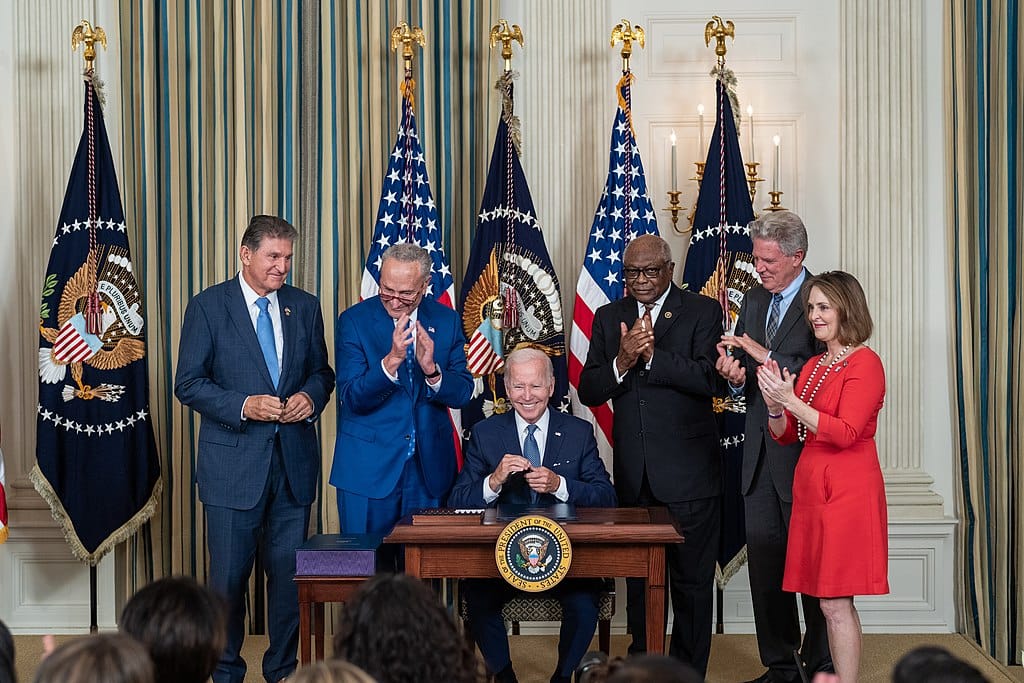
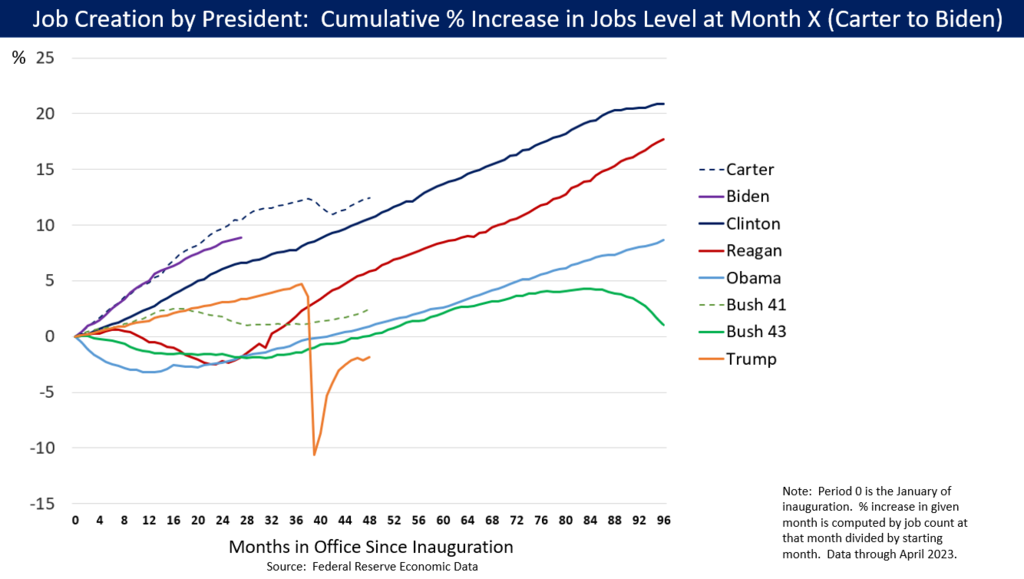
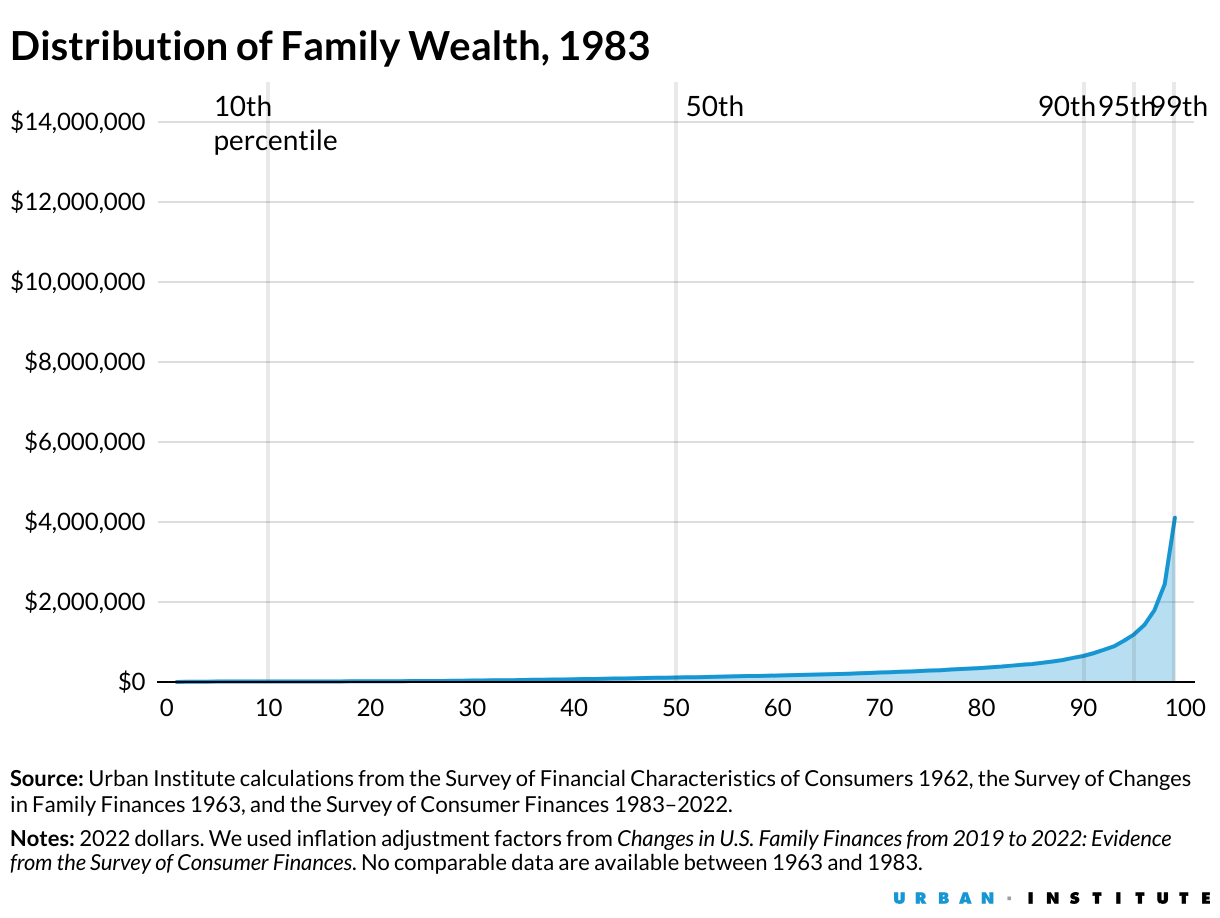
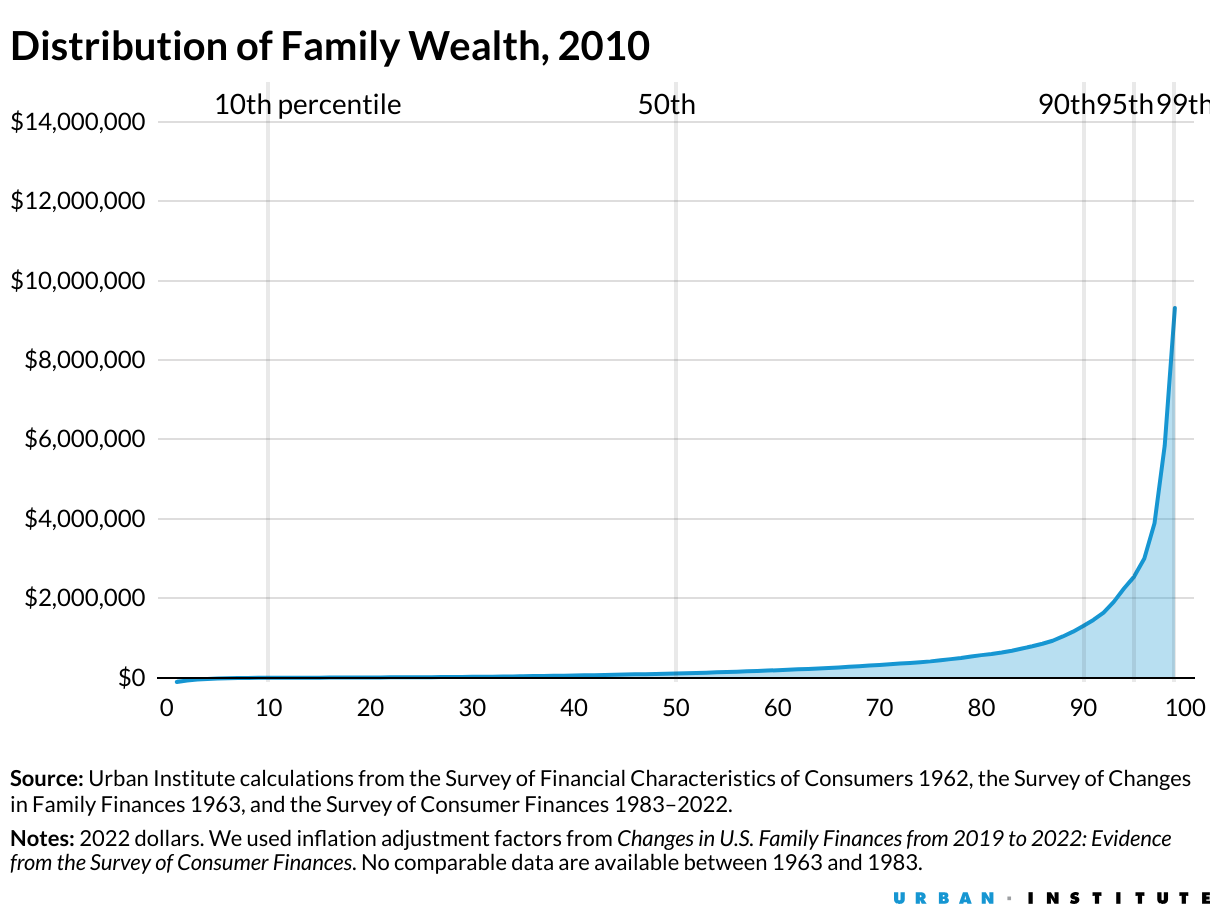
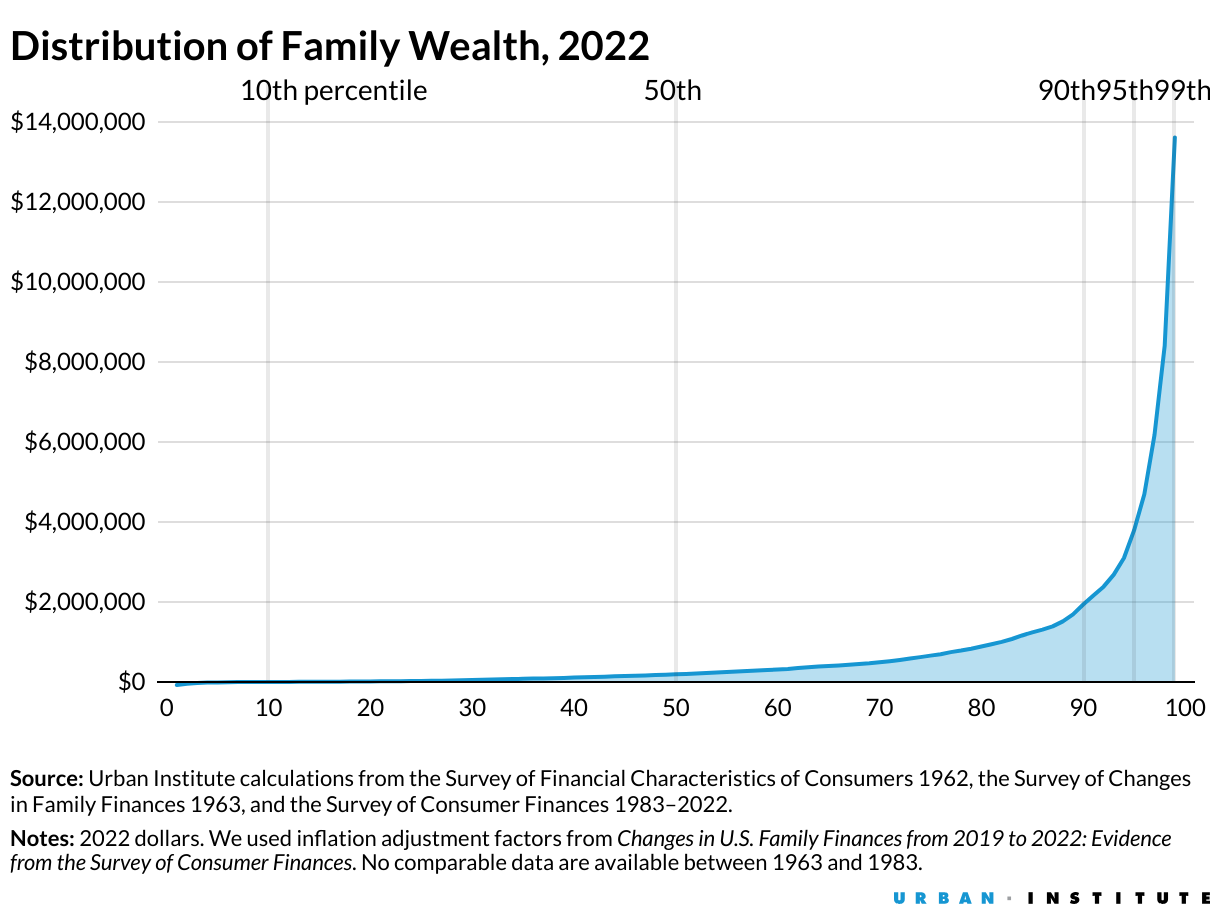


 Poulomi Dasgupta is a Senior Analytics Solutions Architect with AWS. She is passionate about helping customers build cloud-based analytics solutions to solve their business problems. Outside of work, she likes travelling and spending time with her family.
 Ranjan Burman is an Analytics Specialist Solutions Architect at AWS. He specializes in Amazon Redshift and helps customers build scalable analytical solutions. He has more than 16 years of experience in different database and data warehousing technologies. He is passionate about automating and solving customer problems with cloud solutions.
 Jason Pedreza is a Senior Redshift Specialist Solutions Architect at AWS with data warehousing experience handling petabytes of data. Prior to AWS, he built data warehouse solutions at Amazon.com and Amazon Devices. He specializes in Amazon Redshift and helps customers build scalable analytic solutions.
 Agasthi Kothurkar is an AWS Solutions Architect, and is based in Boston. Agasthi works with enterprise customers as they transform their business by adopting the Cloud. Prior to joining AWS, he worked with leading IT consulting organizations on customers engagements spanning Cloud Architecture, Enterprise Architecture, IT Strategy, and Transformation. He is passionate about applying Cloud technologies to resolve complex real world business problems.


 Felix John is a Solutions Architect and data streaming expert at AWS, based in Germany. He focuses on supporting small and medium businesses on their cloud journey. Outside of his professional life, Felix enjoys playing Floorball and hiking in the mountains.
 Michelle Mei-Li Pfister is a Solutions Architect at AWS. She is supporting customers in retail and consumer packaged goods (CPG) industry on their cloud journey. She is passionate about topics around data and machine learning.