Post Syndicated from Matt Granger original https://www.youtube.com/watch?v=Qv1BxslNMME
This Day in History: March 6
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=siKMDLvbGhc
Surveillance through Push Notifications
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/03/surveillance-through-push-notifications.html
The Washington Post is reporting on the FBI’s increasing use of push notification data—”push tokens”—to identify people. The police can request this data from companies like Apple and Google without a warrant.
The investigative technique goes back years. Court orders that were issued in 2019 to Apple and Google demanded that the companies hand over information on accounts identified by push tokens linked to alleged supporters of the Islamic State terrorist group.
But the practice was not widely understood until December, when Sen. Ron Wyden (D-Ore.), in a letter to Attorney General Merrick Garland, said an investigation had revealed that the Justice Department had prohibited Apple and Google from discussing the technique.
[…]
Unlike normal app notifications, push alerts, as their name suggests, have the power to jolt a phone awake—a feature that makes them useful for the urgent pings of everyday use. Many apps offer push-alert functionality because it gives users a fast, battery-saving way to stay updated, and few users think twice before turning them on.
But to send that notification, Apple and Google require the apps to first create a token that tells the company how to find a user’s device. Those tokens are then saved on Apple’s and Google’s servers, out of the users’ reach.
The article discusses their use by the FBI, primarily in child sexual abuse cases. But we all know how the story goes:
“This is how any new surveillance method starts out: The government says we’re only going to use this in the most extreme cases, to stop terrorists and child predators, and everyone can get behind that,” said Cooper Quintin, a technologist at the advocacy group Electronic Frontier Foundation.
“But these things always end up rolling downhill. Maybe a state attorney general one day decides, hey, maybe I can use this to catch people having an abortion,” Quintin added. “Even if you trust the U.S. right now to use this, you might not trust a new administration to use it in a way you deem ethical.”
The Lost Boys of Big Tech
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=65eJwbkR9gg
Fostering collaboration in the Global Clubs Partner network
Post Syndicated from Isabel Ronaldson original https://www.raspberrypi.org/blog/collaboration-global-clubs-partner-network/
We partner with educational organisations around the world to bring coding activities to young people in their regions through Code Club and CoderDojo. Currently involving 52 organisations in 41 countries, this Global Clubs Partner network shares our passion for empowering kids to create with technology.
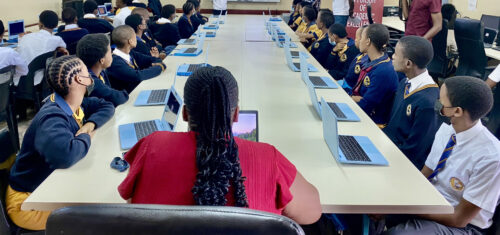
A key aspect of how we foster the Global Clubs Partner network is to promote connections between partners. It’s one reason we host regular online meetings and regional in-person events, and connect partners one on one to facilitate information sharing. Today, we’re highlighting three stories from partner organisations that have benefited from working with each other.
Aruba and the Netherlands
In March 2023, the Foundation hosted the first Clubs Conference for educators and volunteers involved with Code Club and CoderDojo. As this event took place in Cambridge, UK, the majority of attendees were from the UK and Republic or Ireland, but a small number came from further away. Much further away, in some cases.
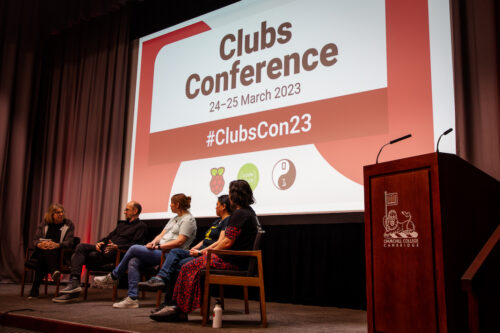
Bruce Harms and his colleague Thanya Croes (Full Stack Vision Foundation, Aruba) were attending the Clubs Conference to share their work to increase digital literacy in Aruba through CoderDojo clubs. At a special conference session for international attendees, they connected with Sanneke van der Meer and Marloes van der Meulen (CoderDojo Netherlands), who were also presenting as part of the session.
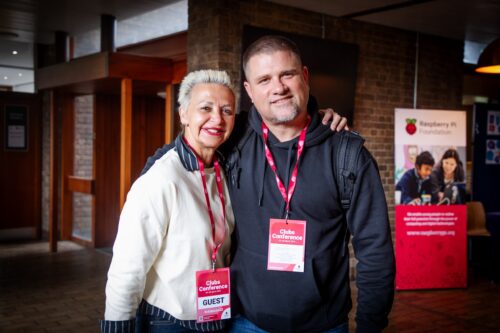
After the Clubs Conference, the two organisations remained in touch. Later in the year, Bruce and Thanya attended the DojoCon Netherlands 2023 in the Hague. ”It was an amazing day with great workshops and lots of other CoderDojo Champions”, Bruce said. He and Thanya have plans to invite the CoderDojo Netherlands team to Aruba and hope to collaborate on future projects together.
Malawi and Tanzania
Sylvester Mtumbuka (Computers for Enhanced Education, Malawi) and Mrisho Habibu (AMCET Innovation Hub, Tanzania) first connected at our Global Clubs Partner meetup in Malaysia in late 2022. Sylvester said: “We were the only ones from Africa there and we are from neighbouring countries. We happen to have a lot of goals in common, and we started discussing possible opportunities for collaboration.”
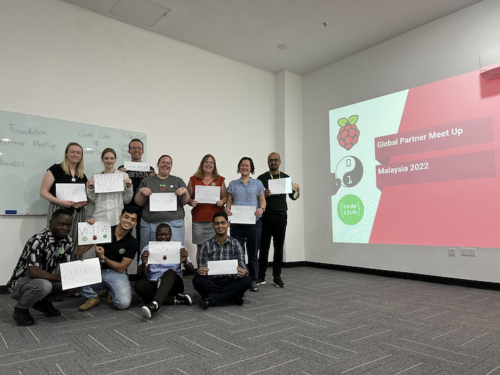
The result is the Tanzania and Malawi (TaMa) Innovation Initiative, which is dedicated to fostering the educational, technological, and entrepreneurial development of young people in Tanzania and Malawi. It aims to empower young people in under-served communities, offering support for sustainable livelihoods and entrepreneurship, and it is already yielding great results.
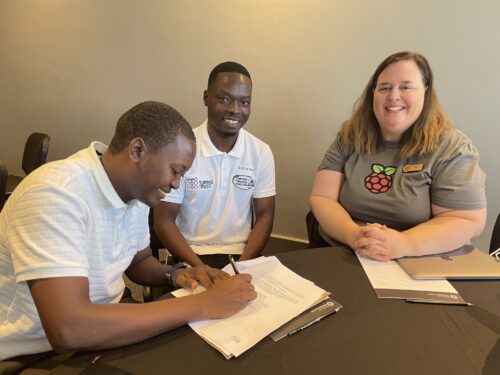
As part of their ongoing partnerships with us, Sylvester and Mrisho attended our Global Clubs Partner meetup in South Africa a year later — the perfect opportunity to sign their partnership agreement.
Greece and Portugal
A chance meeting between Homero Cardoso (TAGUSVALLEY, Portugal) and Manos Zeakis (CoderDojo in Greece) at DojoCon Netherlands 2022 in Almere had unexpected consequences. “We discussed a lot of things, including the difficulty in finding venues for our Dojos in Greece”, Manos said. “Then in October 2023, we met at a Global Clubs Partner call and we talked again. With Homero’s help I contacted a Greek company, and they were immediately enthusiastic about helping us. After a few weeks, the Nea Ionia Dojo was live and the first Ninjas had their first session!”
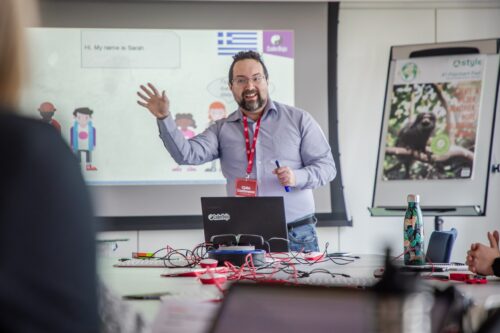
Homero added: “Getting to know Manos was transformative for me as well. Because of that chance encounter in Almere, this year 7th and 8th grade students are participating in Astro Pi Mission Zero for the first time, mostly due to the inspiring example of Manos’s United Dojos project presented at DojoCon.”
Could your organisation become a Global Clubs Partner?
To find out more about our Global Clubs Partner network and how your organisation might get involved, visit the CoderDojo or Code Club websites, or contact us directly about a partnership.
The post Fostering collaboration in the Global Clubs Partner network appeared first on Raspberry Pi Foundation.
Какви да са партидите в Имотния регистър?
Post Syndicated from Bozho original https://blog.bozho.net/blog/4235
Имотен регистър в България има на теория, но на практика няма. Или обратното – на практика има, но не е спазен закона. Това е и становището на Нотариалната камара. Миналата зима бях внесъл текстове в Закона за кадастъра и имотния регистър, които да позволят по-бързо преминаване към истински, пълен имотен регистър, но тогава не намериха подкрепа.
Какво е имотен регистър – по закон това е съвкупността от партидите, свързани с недвижимите имоти. И тук идва въпросът какво е „партида“. Има две „школи“ – едната смята, че партидите трябва да са персонални – т.е. имотите да се описват на база на техния собственик (и да преминават от един към друг собственик), а другата – че трябва да са имотни партиди – т.е. водещото е имотът, а собствениците са атрибути, които се сменят. Всичко до 2009 г. е именно в такива папки в кашони. Към момента електронни имотни партиди по смисъла на закона няма, а правилника за вписванията предвижда персонални партиди в електронния регистър.
Тази дилема – персонални срещу имотни – е напълно валидна в хартиения свят – регистърът представлява документи в папки в кашони и е важно как ще подредиш папките и кашоните, за да може да търсиш в тях. Ако ги подредиш по ЕГН на собственика, ще можеш да търси лесно по собственик. Ако ги подредиш по идентификатор или адрес на имота, ще можеш да търсиш по имот.
В електронния свят, обаче, регистърът се реализира не чрез папки в кашони, а чрез т.нар. система за управление на релационни бази данни. Там може да има таблица с имотни сделки, като за всяка сделка да има една колона „идентификатор на имот“ и една колона „идентификатор на собственик“ и така може да се търси и по двата критерия. Т.е. партидата не е нито персонална, нито имотна. Това се постига чрез т.нар. индекси, които са виртуалната реализация на папките в кашоните – подреждане по определен ред, за да може да бъде търсено по-бързо. („Сделка“, разбира се, е опростено, защото има много хипотези за придобиване – наследство, делба, давност…). Именно така е реализирана информационната система ИКАР, в която след 2009 г. се вписват извършените имотни прехвърляния.
Представете си три групи кашони. В единия са номерата на актовете, а в другите два – ЕГН-та и идентификатори/адреси на имоти, като във вторите два, в папката на всеки човек и на всеки имот се вписват само номерата на актовете от първата група кашони. Това заема доста място и е сложно за водене в хартиения свят. Но в електронните е най-елементарното нещо.
Действащият Закон за кадастъра и имотния регистър предвижда имотни партиди: „чл. 3. (1) Имотният регистър се състои от партидите на недвижимите имоти“. За мен това трябва да се преосмили – имотният регистър е съвкпуността от актовете, с които се признава или прехвърля правото на собственост или се учредява, прехвърля, изменя или прекратява друго вещно право върху недвижими имоти. Логическата организация на тези актове по партиди – имотни и персонални – е подробност. Чрез информационната система на имотния регистър могат да бъдат постигнати целите на партидите без да ги уреждаме нормативно като такива.
Сигурен съм, че това е непопулярно и дори еретично мнение и че „не може ИТ-та да определят как ще работи един толкова важен регистър“. Но смятам, че следва технологичните възможности да бъдат отчетени при избор на концептуалния модел на регистрите – нещо, което е било невъзможно или непрактично преди, сега вече е тривиално. А от позицията на нотариалната камара е видно, че електронен имотен регистър, след толкова години действащ Закон за кадстъра и имотния регистър, официално няма.
По Плана за възстановяване и устойчивост (ПВУ) се предвижда дигитализация на хартиените архиви на Имотния регистър и според мен трябва да обсъдим задълбочено концептуалните положения в закона, за да не се окажем и след това с половин имотен регистър. Защото по ПВУ ще се сканират документи, но тяхната правна стойност ще остане под въпрос. Запазването на настоящия концептуален модел само по себе си не е пречка пред реализирането на истински имотен регистър, но според мен е пречка пред цялостното осмисляне на начина, по който данните се съхраняват и търсят в електронен вид.
Материалът Какви да са партидите в Имотния регистър? е публикуван за пръв път на БЛОГодаря.
Expanding AMD Spartan UltraScale+ Family on 16nm and into the 2040s
Post Syndicated from Cliff Robinson original https://www.servethehome.com/expanding-amd-spartan-ultrascale-family-on-16nm-and-into-the-2040s/
AMD Spartan UltraScale+ FPGAs are out in 16nm process with new features and planned lifecycles well into the 2040s
The post Expanding AMD Spartan UltraScale+ Family on 16nm and into the 2040s appeared first on ServeTheHome.
Bending pause times to your will with Generational ZGC
Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/bending-pause-times-to-your-will-with-generational-zgc-256629c9386b
The surprising and not so surprising benefits of generations in the Z Garbage Collector.
By Danny Thomas, JVM Ecosystem Team
The latest long term support release of the JDK delivers generational support for the Z Garbage Collector.
More than half of our critical streaming video services are now running on JDK 21 with Generational ZGC, so it’s a good time to talk about our experience and the benefits we’ve seen. If you’re interested in how we use Java at Netflix, Paul Bakker’s talk How Netflix Really Uses Java, is a great place to start.
Reduced tail latencies
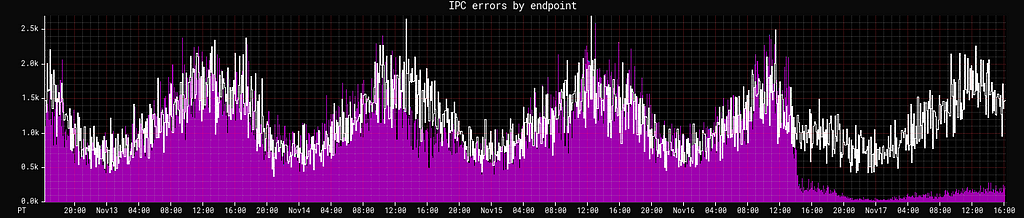
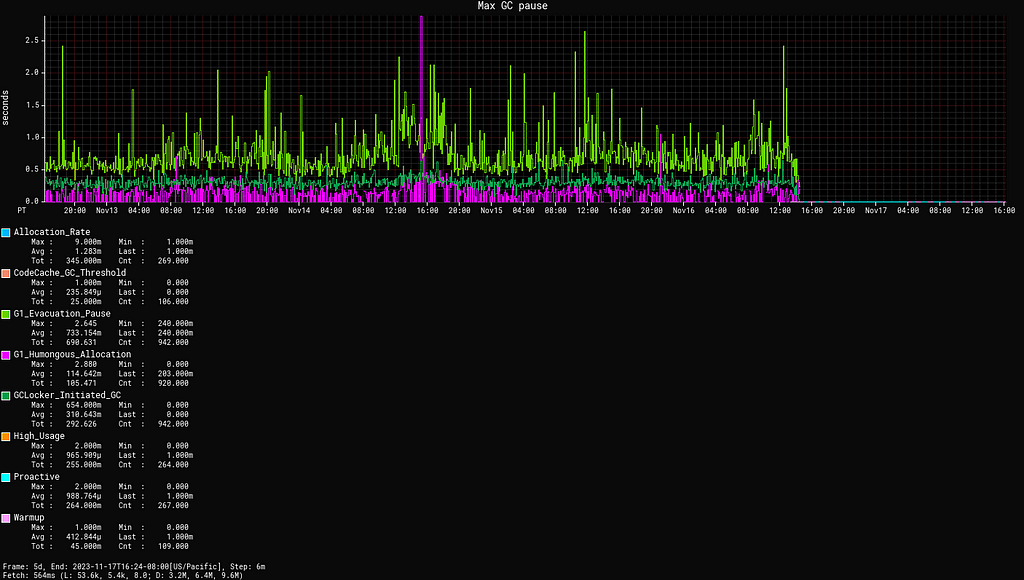
In both our GRPC and DGS Framework services, GC pauses are a significant source of tail latencies. That’s particularly true of our GRPC clients and servers, where request cancellations due to timeouts interact with reliability features such as retries, hedging and fallbacks. Each of these errors is a canceled request resulting in a retry so this reduction further reduces overall service traffic by this rate:
Removing the noise of pauses also allows us to identify actual sources of latency end-to-end, which would otherwise be hidden in the noise, as maximum pause time outliers can be significant:
Efficiency
Even after we saw very promising results in our evaluation, we expected the adoption of ZGC to be a trade off: a little less application throughput, due to store and load barriers, work performed in thread local handshakes, and the GC competing with the application for resources. We considered that an acceptable trade off, as avoiding pauses provided benefits that would outweigh that overhead.
In fact, we’ve found for our services and architecture that there is no such trade off. For a given CPU utilization target, ZGC improves both average and P99 latencies with equal or better CPU utilization when compared to G1.
The consistency in request rates, request patterns, response time and allocation rates we see in many of our services certainly help ZGC, but we’ve found it’s equally capable of handling less consistent workloads (with exceptions of course; more on that below).
Operational simplicity
Service owners often reach out to us with questions about excessive pause times and for help with tuning. We have several frameworks that periodically refresh large amounts of on-heap data to avoid external service calls for efficiency. These periodic refreshes of on-heap data are great at taking G1 by surprise, resulting in pause time outliers well beyond the default pause time goal.
This long lived on-heap data was the major contributor to us not adopting non-generational ZGC previously. In the worst case we evaluated, non-generational ZGC caused 36% more CPU utilization than G1 for the same workload. That became a nearly 10% improvement with generational ZGC.
Half of all services required for streaming video use our Hollow library for on-heap metadata. Removing pauses as a concern allowed us to remove array pooling mitigations, freeing hundreds of megabytes of memory for allocations.
Operational simplicity also stems from ZGC’s heuristics and defaults. No explicit tuning has been required to achieve these results. Allocation stalls are rare, typically coinciding with abnormal spikes in allocation rates, and are shorter than the average pause times we saw with G1.
Memory overhead
We expected that losing compressed references on heaps < 32G, due to colored pointers requiring 64-bits object pointers, would be a major factor in the choice of a garbage collector.
We’ve found that while that’s an important consideration for stop-the-world GCs, that’s not the case for ZGC where even on small heaps, the increase in allocation rate is amortized by the efficiency and operational improvements. Our thanks to Erik Österlund at Oracle for explaining the less intuitive benefits of colored pointers when it comes to concurrent garbage collectors, which lead us to evaluating ZGC more broadly than initially planned.
In the majority of cases ZGC is also able to consistently make more memory available to the application:
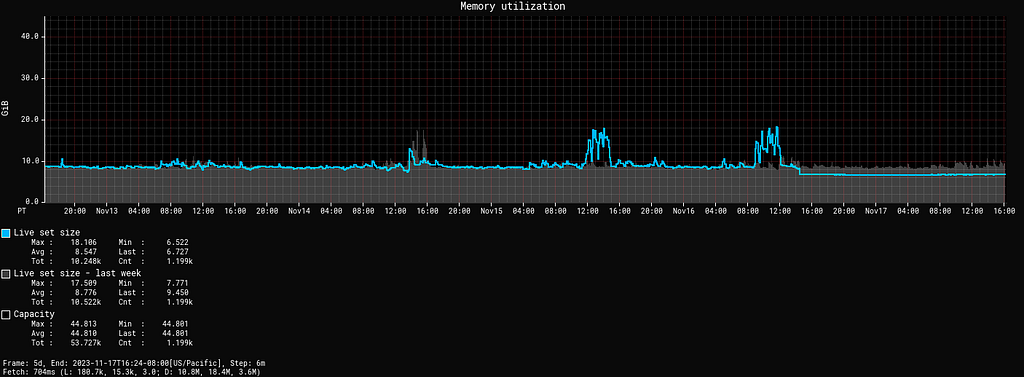
ZGC has a fixed overhead 3% of the heap size, requiring more native memory than G1. Except in a couple of cases, there’s been no need to lower the maximum heap size to allow for more headroom, and those were services with greater than average native memory needs.
Reference processing is also only performed in major collections with ZGC. We paid particular attention to deallocation of direct byte buffers, but we haven’t seen any impact thus far. This difference in reference processing did cause a performance problem with JSON thread dump support, but that’s a unusual situation caused by a framework accidentally creating an unused ExecutorService instance for every request.
Transparent huge pages
Even if you’re not using ZGC, you probably should be using huge pages, and transparent huge pages is the most convenient way to use them.
ZGC uses shared memory for the heap and many Linux distributions configure shmem_enabled to never, which silently prevents ZGC from using huge pages with -XX:+UseTransparentHugePages.
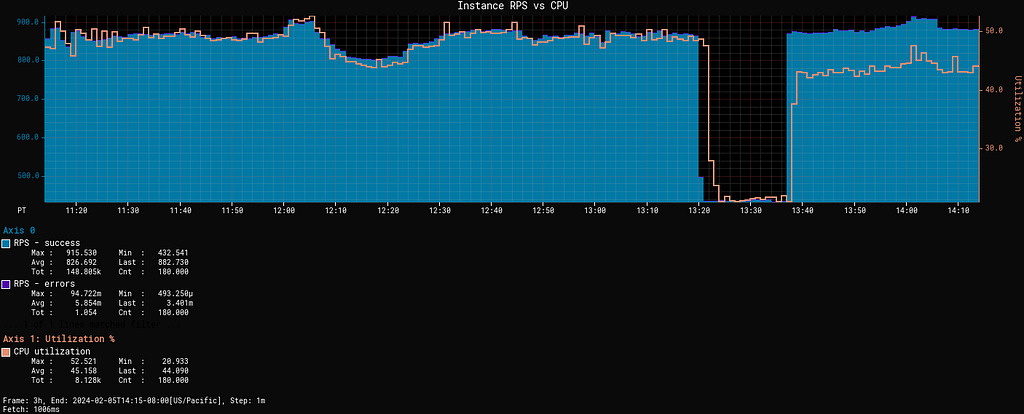
Here we have a service deployed with no other change but shmem_enabled going from never to advise, reducing CPU utilization significantly:
Our default configuration:
- Sets heap minimum and maximums to equal size
- Configures -XX:+UseTransparentHugePages -XX:+AlwaysPreTouch
- Uses the following transparent_hugepage configuration:
echo madvise | sudo tee /sys/kernel/mm/transparent_hugepage/enabled
echo advise | sudo tee /sys/kernel/mm/transparent_hugepage/shmem_enabled
echo defer | sudo tee /sys/kernel/mm/transparent_hugepage/defrag
echo 1 | sudo tee /sys/kernel/mm/transparent_hugepage/khugepaged/defrag
What workloads weren’t a good fit?
There is no best garbage collector. Each trades off collection throughput, application latency and resource utilization depending on the goal of the garbage collector.
For the workloads that have performed better with G1 vs ZGC, we’ve found that they tend to be more throughput oriented, with very spiky allocation rates and long running tasks holding objects for unpredictable periods.
A notable example was a service where very spiky allocation rates and large numbers of long lived objects, which happened to be a particularly good fit for G1’s pause time goal and old region collection heuristics. It allowed G1 to avoid unproductive work in GC cycles that ZGC couldn’t.
The switch to ZGC by default has provided the perfect opportunity for application owners to think about their choice of garbage collector. Several batch/precompute cases had been using G1 by default, where they would have seen better throughput from the parallel collector. In one large precompute workload we saw a 6–8% improvement in application throughput, shaving an hour off the batch time, versus G1.
Try it for yourself!
Left unquestioned, assumptions and expectations could have caused us to miss one of the most impactful changes we’ve made to our operational defaults in a decade. We’d encourage you to try generational ZGC for yourself. It might surprise you as much as it surprised us.

Bending pause times to your will with Generational ZGC was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
Comic for 2024.03.06 – Fight This
Post Syndicated from Explosm.net original https://explosm.net/comics/fight-this
New Cyanide and Happiness Comic
Earth/Venus Venn Diagram
Post Syndicated from xkcd.com original https://xkcd.com/2903/
Love in Taipei | Abigail Hing Wen, Ashley Liao & Chelsea Zhang | Talks at Google
Post Syndicated from Talks at Google original https://www.youtube.com/watch?v=11RZPF-4FXE
Жена начело на държавата? Хубаво е, но не е достатъчно
Post Syndicated from Светла Енчева original https://www.toest.bg/zhena-nachelo-na-durzhavata-hubavo-e-no-ne-e-dostatuchno/

Освен че е Международният ден на жените, тазгодишният 8 март е и крайният срок, който председателят на ГЕРБ Бойко Борисов даде на ПП–ДБ, за да постигнат съгласие за ротацията на правителството. Ако успеят, България ще има за втори път министър-председателка – след служебното правителство на Ренета Инджова от 1994 г., тоест точно преди 30 години. И за първи път в историята на страната жена ще застане начело на редовен кабинет. Ако некоалиционните партньори не успеят да се разберат, ще се стигне до нови избори. При такъв сценарий шансът Мария Габриел да заеме премиерския пост ще остане, но няма да е толкова голям.
Жени начело на държавите си
Три балкански страни са изпреварили България и в тях вече има жени на върха на държавата, като само една от тях е в ЕС. Боряна Крищо е министър-председателка на Босна и Херцеговина, Ана Бърнабич – на Сърбия, а Катерина Сакеларопулу е президентка на Гърция.
В световен план обаче от близо 200 държави в по-малко от 30 на върха стоят жени. При това част от длъжностите са по-скоро представителни, отколкото действително ръководни. Президентът на Унгария (доскоро на поста беше Каталин Новак) има представителни функции, а реалната власт се упражнява от премиера Виктор Орбан. Макар Сърбия да е парламентарна република, силната политическа фигура в страната е президентът (понастоящем – Александър Вучич). Той назначава и премиерите. В Италия обаче министър-председателят въплъщава реалната власт, така че Джорджа Мелони действително ръководи страната.
Три жени, чието управление остана в историята през последните години
В края на 2021 г. в Германия приключи 16-годишната ера на Ангела Меркел. Тя е не само първата жена федерален канцлер в страната, но и първият човек от бившата ГДР на този пост.
При всички критики към управлението на Меркел, немалко от тях – основателни, тя излъчваше впечатляваща стабилност, която успяваше да предаде на гражданите, казвайки точните думи в точния момент. Приемането на над милион бежанци в страната може и да допринесе за възхода на крайната десница, но знаменитата ѝ реплика от 2015 г. „Ще се справим“ беше от голямо значение за т.нар. култура на приемане. По време на най-строгите мерки заради пандемията от COVID-19 тя намираше думите и верния тон, така че хем да обясни на хората колко сериозно е положението, хем да ги накара да се почувстват в сигурни ръце.
Няма база за сравнение между увереността, излъчвана от Меркел, и поведението на настоящия канцлер Олаф Шолц.
За разлика от Ангела Меркел, Сана Марин беше министър-председателка на Финландия по-малко от 4 години – от края на 2019 г. до средата на 2023 г. Но на 34 г. тя стана най-младият държавен лидер в света, освен това управляваше с предимно женски екип.
Въпреки че на Марин се налагаше да се справя със сериозни кризи, като пандемията и войната в Украйна (нейното правителство предлага Финландия да влезе в НАТО), поведението ѝ беше обект на по същество сексистки критики, че не е достатъчно сериозно. Тя беше критикувана, че изглежда като „рок звезда“, а изтекло видео от частно парти, на което се вижда как пие и танцува, предизвика сериозен скандал. „Аз съм човек. И аз също понякога копнея за радост, светлина и забавление“, каза тогава тя.
На изборите през 2023 г. Марин загуби, а премиер стана умерен консерватор, който е дългогодишен политик и прилича на такъв, а не на рок звезда.
Доскорошната министър-председателка на Нова Зеландия Джасинда Ардърн зае поста на 37-годишна възраст и беше втората жена в света след Беназир Бхуто, родила дете, докато е на тази позиция. Тя се противопоставяше на изолационизма, протекционизма и расизма, характерни за управлението на Доналд Тръмп, и също като Сана Марин отстояваше феминистки ценности.
Мерките на Ардърн за ограничаване на пандемията бяха изключително успешни за демократична страна – през 2020 г. в продължение на цели 102 дни след 1 май нямаше нито един случай на вътрешно предаване на вируса в страната.
След пет години и половина на поста тя сама подаде оставка. По собственото ѝ признание – поради изтощение. Лявоцентристката ѝ партия спечели следващите парламентарни избори и получи абсолютно мнозинство в парламента, което е признание за успешното управление на Джасинда Ардърн.
Не всичко е цветя и рози
Въпреки добрите примери управлението на една държава от жена не е по дефиниция добро, нито пък е гаранция за положителни промени за жените в съответната страна. Това важи впрочем за всички области, например за местната власт. Столицата на България 14 години се управляваше от жена – Йорданка Фандъкова. Но за този период градската среда не стана по-достъпна за бебешки колички (а те се бутат предимно от жени), а въпреки всички обещания за справяне с недостига на места в детските градини проблемът си остана.
По време на управлението на Ангела Меркел за жените в Германия, особено в западната ѝ част, не стана много по-лесно да съчетават отглеждането на дете с работата – дори да успеят да запишат детето в градина, тя в общия случай затваря в ранния следобед, което прави невъзможно за много жени да работят на пълен ден.
Джорджа Мелони е първата жена премиер на Италия. Иронично, основаната от нея крайнодясна партия се казва „Италиански братя“ – сестри в името няма. Мелони все пак се опитва, доколкото това е възможно за сексистки електорат, какъвто преобладаващо са крайнодесните избиратели, да въведе известни подобрения в живота на италианските жени – например по-добра защита от домашно насилие и по-високи детски надбавки. В същото време обаче въведените от управлението ѝ политики стимулират жените по-скоро да си стоят вкъщи и да си гледат децата, отколкото да се развиват професионално.
Доскорошната президентка на Унгария Каталин Новак, която заедно с българския президент Румен Радев и сръбския му колега Александър Вучич подписа новогодишно изявление в защита на семейството, безславно подаде оставка. Това стана поради скандал, че е помилвала затворник, осъден за допускане на педофилия в институция за деца.
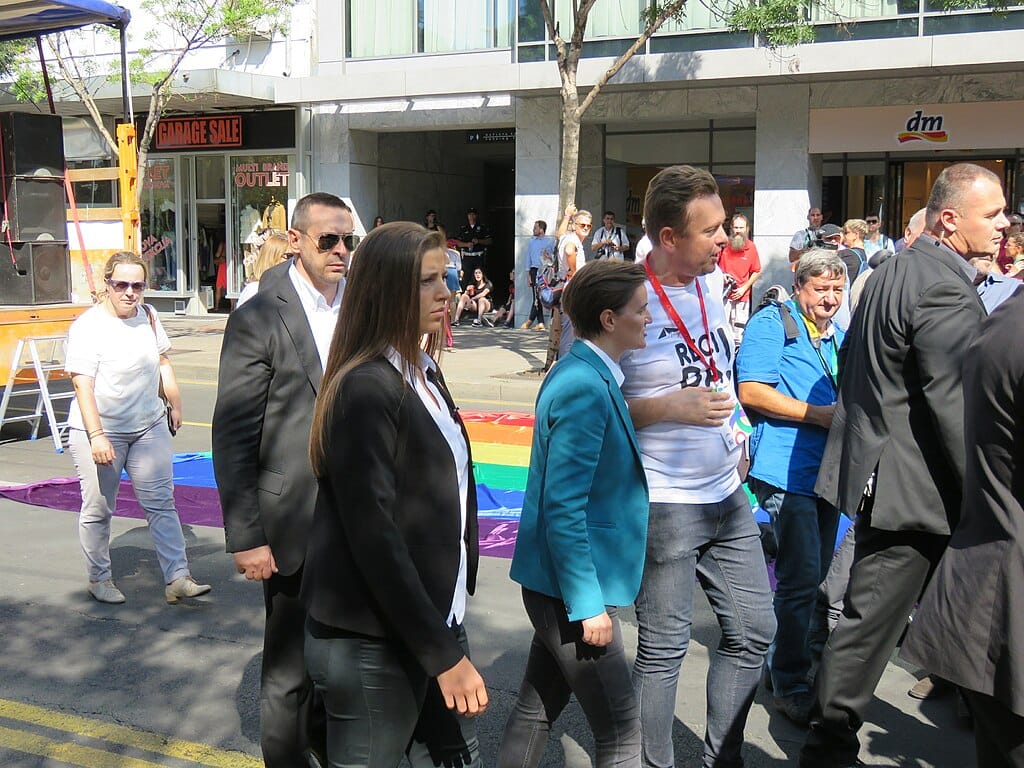
Засега сръбската министър-председателка Ана Бърнабич стои стабилно на поста си, но с цената на компромиси. Открито хомосексуална, тя допринесе за известно нормализиране на отношението към ЛГБТИ хората в страната, в която агресивните хомофобски прояви не са рядкост. Като премиер е вземала участие в белградския прайд, а през 2019 г. партньорката ѝ роди дете. В същото време тя не се противопоставя решително на политиката на Вучич за близки отношения с режима на Владимир Путин, в който ЛГБТИ хората се преследват като екстремисти и се върви към забрана на абортите.
Жени стоят начело и на някои африкански страни, в които има сериозни проблеми с насилието над жени. Включително в Етиопия, където все още е широко разпространено женското обрязване, наричано още генитално осакатяване.
Важно, но недостатъчно условие
Да обобщим. Наличието на жени сред световните лидери е важно дори само заради това, че овластява жените – показва им, че не е невъзможно да се изкачат на най-високите позиции във властовата йерархия. Но то не е гаранция за напредък в постигането на равни права, защото политиката не е функция на пола.
Ето например с похода си срещу Истанбулската конвенция председателката на БСП Корнелия Нинова изигра сериозна роля за връщането на борбата с насилието над жени години назад. А жените – членове на Конституционния съд, дружно подкрепиха решението, според което социалната роля на жената, съгласно Конституцията, е да бъде майка.
Засега Мария Габриел не дава признаци, че смята да се еманципира от сянката на Бойко Борисов и да бъде нещо повече от приемлива за Брюксел негова маска. Но това впечатление може да е погрешно и Габриел да се окаже изненада за всички, най-вече за Борисов, като провежда политика в съответствие с европейските стандарти за човешки права, включително права на жените. И да има смелост да се бори със задкулисната власт, поради която всеки опит за прогрес буксува.
Но засега, както би казала Йорданка Фандъкова, положението е „хубаво е, но не е готово“. По-точно – не е достатъчно.
Bring your workforce identity to Amazon EMR Studio and Athena
Post Syndicated from Manjit Chakraborty original https://aws.amazon.com/blogs/big-data/bring-your-workforce-identity-to-amazon-emr-studio-and-athena/
Customers today may struggle to implement proper access controls and auditing at the user level when multiple applications are involved in data access workflows. The key challenge is to implement proper least-privilege access controls based on user identity when one application accesses data on behalf of the user in another application. It forces you to either give all users broad access through the application with no auditing, or try to implement complex bespoke solutions to map roles to users.
Using AWS IAM Identity Center, you can now propagate user identity to a set of AWS services and minimize the need to build and maintain complex custom systems to vend roles between applications. IAM Identity Center also provides a consolidated view of users and groups in one place that the interconnected applications can use for authorization and auditing.
IAM Identity Center enables centralized management of user access to AWS accounts and applications using identity providers (IDPs) like Okta. This allows users to log in one time with their existing corporate credentials and seamlessly access downstream AWS services supporting identity propagation. With IAM Identity Center, Okta user identities and groups can be automatically synced using SCIM 2.0 for accurate user information in AWS.
Amazon EMR Studio is a unified data analysis environment where you can develop data engineering and data science applications. You can now develop and run interactive queries on Amazon Athena from EMR Studio (for more details, refer to Amazon EMR Studio adds interactive query editor powered by Amazon Athena ). Athena users can access EMR Studio without logging in to the AWS Management Console by enabling federated access from your IdP via IAM Identity Center. This removes the complexity of maintaining different identities and mapping user roles across your IdP, EMR Studio, and Athena.
You can govern Athena workgroups based on user attributes from Okta to control query access and costs. AWS Lake Formation can also use Okta identities to enforce fine-grained access controls through granting and revoking permissions.
IAM Identity Center and Okta single sign-on (SSO) integration streamlines access to EMR Studio and Athena with centralized authentication. Users can have a familiar sign-in experience with their workforce credentials to securely run queries in Athena. Access policies on Athena workgroups and Lake Formation permissions provide governance based on Okta user profiles.
This blog post explains how to enable single sign-on to EMR Studio using IAM Identity Center integration with Okta. It shows how to propagate Okta identities to Athena and Lake Formation to provide granular access controls on queries and data. The solution streamlines access to analytics tools with centralized authentication using workforce credentials. It leverages AWS IAM Identity Center, Amazon EMR Studio, Amazon Athena, and AWS Lake Formation.
Solution overview
IAM Identity Center allows users to connect to EMR Studio without needing administrators to manually configure AWS Identity and Access Management (IAM) roles and permissions. It enables mapping of IAM Identity Center groups to existing corporate identity roles and groups. Admins can then assign privileges to roles and groups and assign users to them, enabling granular control over user access. IAM Identity Center provides a central repository of all users in AWS. You can create users and groups directly in IAM Identity Center or connect existing users and groups from providers like Okta, Ping Identity, or Azure AD. It handles authentication through your chosen identity source and maintains a user and group directory for EMR Studio access. Known user identities and logged data access facilitates compliance through auditing user access in AWS CloudTrail.
The following diagram illustrates the solution architecture.

The EMR Studio workflow consists of the following high-level steps:
- The end-user launches EMR Studio using the AWS access portal URL. This URL is provided by an IAM Identity Center administrator via the IAM Identity Center dashboard.
- The URL redirects the end-user to the workforce IdP Okta, where the user enters workforce identity credentials.
- After successful authentication, the user will be logged in to the AWS console as a federated user.
- The user opens EMR Studio and navigates to the Athena query editor using the link available on EMR Studio.
- The user selects the correct workgroup as per the user role to run Athena queries.
- The query results are stored in separate Amazon Simple Storage Service (Amazon S3) locations with a prefix that is based on user identity.
To implement the solution, we complete the following steps:
- Integrate Okta with IAM Identity Center to sync users and groups.
- Integrate IAM Identity Center with EMR Studio.
- Assign users or groups from IAM Identity Center to EMR Studio.
- Set up Lake Formation with IAM Identity Center.
- Configure granular role-based entitlements using Lake Formation on propagated corporate identities.
- Set up workgroups in Athena for governing access.
- Set up Amazon S3 access grants for fine-grained access to Amazon S3 resources like buckets, prefixes, or objects.
- Access EMR Studio through the AWS access portal using IAM Identity Center.
- Run queries on the Athena SQL editor in EMR Studio.
- Review the end-to-end audit trail of workforce identity.
Prerequisites
To follow along this post, you should have the following:
- An AWS account – If you don’t have one, you can sign up here.
- An Okta account that has an active subscription – You need an administrator role to set up the application on Okta. If you’re new to Okta, you can sign up for a free trial or a developer account.
For instructions to configure Okta with IAM Identity Center, refer to Configure SAML and SCIM with Okta and IAM Identity Center.
Integrate Okta with IAM Identity Center to sync users and groups
After you have successfully synced users or groups from Okta to IAM Identity Center, you can see them on the IAM Identity Center console, as shown in the following screenshot. For this post, we created and synced two user groups:
- Data Engineer
- Data Scientists

Next, create a trusted token issuer in IAM Identity Center:
- On the IAM Identity Center console, choose Settings in the navigation pane.
- Choose Create trusted token issuer.
- For Issuer URL, enter the URL of the trusted token issuer.
- For Trusted token issuer name, enter Okta.
- For Map attributes¸ map the IdP attribute Email to the IAM Identity Center attribute Email.
- Choose Create trusted token issuer.


The following screenshot shows your new trusted token issuer on the IAM Identity Center console.

Integrate IAM Identity Center with EMR Studio
We start with creating a trusted identity propagation enabled in EMR Studio.
An EMR Studio administrator must perform the steps to configure EMR Studio as an IAM Identity Center-enabled application. This enables EMR Studio to discover and connect to IAM Identity Center automatically to receive sign-in and user directory services.
The point of enabling EMR Studio as an IAM Identity Center-managed application is so you can control user and group permissions from within IAM Identity Center or from a source third-party IdP that’s integrated with it (Okta in this case). When your users sign in to EMR Studio, for example data-engineer or data-scientist, it checks their groups in IAM Identity Center, and these are mapped to roles and entitlements in Lake Formation. In this manner, a group can map to a Lake Formation database role that allows read access to a set of tables or columns.
The following steps show how to create EMR Studio as an AWS-managed application with IAM Identity Center, then we see how the downstream applications like Lake Formation and Athena propagate these roles and entitlements using existing corporate credentials.
- On the Amazon EMR console, navigate to EMR Studio.
- Choose Create a Studio.
- For Setup options, select Custom.
- For Studio name, enter a name.
- For S3 location for Workspace storage, select Select existing location and enter the Amazon S3 location.

6. Configure permission details for the EMR Studio.
Note that when you choose View permission details under Service role, a new pop-up window will open. You need to create an IAM role with the same policies as shown in the pop-up window. You can use the same for your service role and IAM role.

- On the Create a Studio page, for Authentication, select AWS IAM Identity Center.
- For User role, choose your user role.
- Under Trusted identity propagation, select Enable trusted identity propagation.
- Under Application access, select Only assigned users and groups.
- For VPC, enter your VPC.
- For Subnets, enter your subnet.
- For Security and access, select Default security group.
- Choose Create Studio.

You should now see an IAM Identity Center-enabled EMR Studio on the Amazon EMR console.

After the EMR Studio administrator finishes creating the trusted identity propagation-enabled EMR Studio and saves the configuration, the instance of the EMR Studio appears as an IAM Identity Center-enabled application on the IAM Identity Center console.

Assign users or groups from IAM Identity Center to EMR Studio
You can assign users and groups from your IAM Identity Center directory to the EMR Studio application after syncing with IAM. The EMR Studio administrator decides which IAM Identity Center users or groups to include in the app. For example, if you have 10 total groups in IAM Identity Center but don’t want all of them accessing this instance of EMR Studio, you can select which groups to include in the EMR Studio-enabled IAM app.
The following steps assign groups to EMR Studio-enabled IAM Identity Center application:
- On the EMR Studio console, navigate to the new EMR Studio instance.
- On the Assigned groups tab, choose Assign groups.
- Choose which IAM Identity Center groups you want to include in the application. For example, you may choose the Data-Scientist and Data-Engineer groups.
- Choose Done.
This allows the EMR Studio administrator to choose specific IAM Identity Center groups to be assigned access to this specific instance integrated with IAM Identity Center. Only the selected groups will be synced and given access, not all groups from the IAM Identity Center directory.

Set up Lake Formation with IAM Identity Center
To set up Lake Formation with IAM Identity Center, make sure that you have configured Okta as the IdP for IAM Identity Center, and confirm that the users and groups form Okta are now available in IAM Identity Center. Then complete the following steps:
- On the Lake Formation console, choose IAM Identity Center Integration under Administration in the navigation pane.
You will see the message “IAM Identity Center enabled” along with the ARN for the IAM Identity Center application.
- Choose Create.
In a few minutes, you will see a message indicating that Lake Formation has been successfully integrated with your centralized IAM identities from Okta Identity Center. Specifically, the message will state “Successfully created identity center integration with application ARN,” signifying the integration is now in place between Lake Formation and the identities managed in Okta.

Configure granular role-based entitlements using Lake Formation on propagated corporate identities
We will now set up granular entitlements for our data access in Lake Formation. For this post, we summarize the steps needed to use the existing corporate identities on the Lake Formation console to provide relevant controls and governance on the data, which we will later query through the Athena query editor. To learn about setting up databases and tables in Lake Formation, refer to Getting started with AWS Lake Formation
This post will not go into the full details about Lake Formation. Instead, we will focus on a new capability that has been introduced in Lake Formation—the ability to set up permissions based on your existing corporate identities that are synchronized with IAM Identity Center.
This integration allows Lake Formation to use your organization’s IdP and access management policies to control permissions to data lakes. Rather than defining permissions from scratch specifically for Lake Formation, you can now rely on your existing users, groups, and access controls to determine who can access data catalogs and underlying data sources. Overall, this new integration with IAM Identity Center makes it straightforward to manage permissions for your data lake workloads using your corporate identities. It reduces the administrative overhead of keeping permissions aligned across separate systems. As AWS continues enhancing Lake Formation, features like this will further improve its viability as a full-featured data lake management environment.
In this post, we created a database called zipcode-db-tip and granted full access to the user group Data-Engineer to query on the underlying table in the database. Complete the following steps:
- On the Lake Formation console, choose Grant data lake permissions.
- For Principals, select IAM Identity Center.
- For Users and groups, select Data-Engineer.
- For LF-Tags or catalog resources, select Named Data Catalog resources.
- For Databases, choose
zipcode-db-tip. - For Tables, choose
tip-zipcode.


Similarly, we need to provide the relevant access on the underlying tables to the users and groups for them to be able to query on the data.
- Repeat the preceding steps to provide access to the Data-Engineer group to be able to query on the data.
- For Table permissions, select Select, Describe, and Super.
- For Data permissions, select All data access.
You can grant selective access on rows and comments as per your specific requirements.

Set up workgroups in Athena
Athena workgroups are an AWS feature that allows you to isolate data and queries within an AWS account. It provides a way to segregate data and control access so that each group can only access the data that is relevant to them. Athena workgroups are useful for organizations that want to restrict access to sensitive datasets or help prevent queries from impacting each other. When you create a workgroup, you can assign users and roles to it. Queries launched within a workgroup will run with the access controls and settings configured for that workgroup. They enable governance, security, and resource controls at a granular level. Athena workgroups are an important feature for managing and optimizing Athena usage across large organizations.
In this post, we create a workgroup specifically for members of our Data Engineering team. Later, when logged in under Data Engineer user profiles, we run queries from within this workgroup to demonstrate how access to Athena workgroups can be restricted based on the user profile. This allows governance policies to be enforced, making sure users can only access permitted datasets and queries based on their role.
- On the Athena console, choose Workgroups under Administration in the navigation pane.
- Choose Create workgroup.
- For Authentication, select AWS Identity Center.
- For Service role to authorize Athena, select Create and use a new service role.
- For Service role name, enter a name for your role.

- For Location of query result, enter an Amazon S3 location for saving your Athena query results.

This is a mandatory field when you specify IAM Identity Center for authentication.

After you create the workgroup, you need to assign users and groups to it. For this post, we create a workgroup named data-engineer and assign the group Data-Engineer (propagated through the trusted identity propagation from IAM Identity Center).
- On the Groups tab on the data-engineer details page, select the user group to assign and choose Assign groups.


Set up Amazon S3 access grants to separate the query results for each workforce identity
Next, we set up Amazon S3 grants.
You can watch the following video to set up the grants or refer to Use Amazon EMR with S3 Access Grants to scale Spark access Amazon S3 for instructions.
Initiate login through AWS federated access using the IAM Identity Center access portal
Now we’re ready to connect to EMR Studio and federated login using IAM Identity Center authentication:
- On the IAM Identity Center console, navigate to the dashboard and choose the AWS access portal URL.
- A browser pop-up directs you to the Okta login page, where you enter your Okta credentials.
- After successful authentication, you’ll be logged in to the AWS console as a federated user.
- Choose the EMR Studio application.
- After you federate to EMR Studio, choose Query Editor in the navigation pane to open a new tab with the Athena query editor.
The following video shows a federated user using the AWS access portal URL to access EMR Studio using IAM Identity Center authentication.
Run queries with granular access on the editor
On EMR Studio, the user can open the Athena query editor and then specify the correct workgroup in the query editor to run the queries.

The data engineer can query only the tables on which the user has access. The query results will appear under the S3 prefix, which is separate for each workforce identity.
Review the end-to-end audit trail of workforce identity
The IAM Identity Center administrator can look into the downstream apps that are trusted for identity propagation, as shown in the following screenshot of the IAM Identity Center console.

On the CloudTrail console, the event history displays the event name and resource accessed by the specific workforce identity.

When you choose an event in CloudTrail, the auditors can see the unique user ID that accessed the underlying AWS Analytics services.
Clean up
Complete the following steps to clean up your resources:
- Delete the Okta applications that you created to integrate with IAM Identity Center.
- Delete IAM Identity Center configuration.
- Delete the EMR Studio that you created for testing.
- Delete the IAM role that you created for IAM Identity Center and EMR Studio integration.
Conclusion
In this post, we showed you a detailed walkthrough to bring your workforce identity to EMR Studio and propagate the identity to connected AWS applications like Athena and Lake Formation. This solution provides your workforce with a familiar sign-in experience, without the need to remember additional credentials or maintain complex role mapping across different analytics systems. In addition, it provides auditors with end-to-end visibility into workforce identities and their access to analytics services.
To learn more about trusted identity propagation and EMR Studio, refer to Integrate Amazon EMR with AWS IAM Identity Center.
About the authors
 Manjit Chakraborty is a Senior Solutions Architect at AWS. He is a Seasoned & Result driven professional with extensive experience in Financial domain having worked with customers on advising, designing, leading, and implementing core-business enterprise solutions across the globe. In his spare time, Manjit enjoys fishing, practicing martial arts and playing with his daughter.
 Neeraj Roy is a Principal Solutions Architect at AWS based out of London. He works with Global Financial Services customers to accelerate their AWS journey. In his spare time, he enjoys reading and spending time with his family.
NEW! Try the UI Product Selector #homelab #tech #unifi #shorts
Post Syndicated from Crosstalk Solutions original https://www.youtube.com/watch?v=4Zufk2FxglE
How Much Storage Do I Need to Back Up My Video Surveillance Footage?
Post Syndicated from Tonya Comer original https://www.backblaze.com/blog/how-much-storage-do-i-need-to-backup-my-video-surveillance-footage/
We all have things we want to protect, and if you’re responsible for physically or virtually protecting a business from all types of threats, you probably have some kind of system in place to monitor your physical space. If you’ve ever dealt with video surveillance footage, you know managing it can be a monumental task. Ensuring the safety and security of monitored spaces relies on collecting, storing, and analyzing large amounts of data from cameras, sensors, and other devices. The requirements to back up and retain footage to support investigations are only getting more stringent. Anyone dealing with surveillance data, whether in business or security, needs to ensure that surveillance data is not only backed up, but also protected and accessible.
In this post, we’ll talk through why you should back up surveillance footage, the factors you should consider to understand how much storage you need, and how you can use cloud storage in your video surveillance backup strategy.
The Importance of Backing Up Video Surveillance Footage
Backup storage plays a critical part in maintaining the security of video surveillance footage. Here’s why it’s so important:
- Risk Reduction: Without backup storage, surveillance system data stored on a single hard drive or storage device is susceptible to crashes, corruption, or theft. Having a redundant copy ensures that critical footage is not lost in case of system failures or data corruption.
- Fast Recovery: Video surveillance systems rely on continuous recording to monitor and record all activities. In the event of system failures, backup storage enables swift recovery, minimizing downtime and ensuring uninterrupted surveillance.
- Compliance and Legal Requirements: Many industries, including security, have legal obligations to retain surveillance footage for a specified duration. Backup storage ensures compliance with these requirements and provides evidence when needed.
- Verification and Recall: Backup recordings allow you to verify actions, recall events, and keep track of activities. Having access to historical footage is valuable for potential investigations and future decision making.
Each piece of information about video surveillance requirements will affect how much space your video files take up and, consequently, your storage requirements. Let’s walk through each of these general requirements so you don’t end up underestimating how much backup storage you’ll need.
Video Surveillance Storage Considerations
When you’re implementing a backup strategy for video surveillance, there are several factors that can impact your choices. The number and resolution of cameras, frame rates, retention periods, and more can influence how you design your backup storage system. Consider the following factors when thinking about how much storage you’ll need for your video surveillance footage:
- Placement and Coverage: When it comes to video surveillance camera placement, strategic positioning is crucial for optimal security and regulatory compliance. Consider ground floor doors and windows, main stairs or hallways, common areas, and driveways. Install cameras both inside and outside entry points. Generally, the wider the field of view, the fewer cameras you’ll likely need overall. The FBI provides extensive recommendations for setting up your surveillance system properly.
- Resolution: The resolution determines the clarity of the video footage, which is measured in the number of pixels (px). A higher resolution means more pixels and a sharper image. While there’s no universal minimum for admissible surveillance footage, a resolution of 480 x 640 px is recommended. However, mandated minimums can differ based on local regulations and specific use cases. Note that some regulations may not provide a minimum resolution requirement, and some minimum requirements may not meet the intended purpose of surveillance. Often, it’s better to go with a camera that can record at a higher resolution than the mandated minimum.
- Frame Rate: All videos are made up of individual frames. A higher frame rate—measured in frames per second (FPS)—means a smoother, less clunky image. This is because there are more frames being packed into each second. Like your cameras’ resolution, there are no universal requirements specified by regulations. However, it’s better to go with a camera that can record at a higher FPS so that you have more images to choose from if there’s ever an open investigation.
- Recording Length: Surveillance cameras are required to run all day, every day, which requires a lot of storage. To help reduce the instance of storing videos that aren’t of interest, some cameras can come with artificial intelligence (AI) tools that will only record footage when it identifies something of interest, such as movement or a vehicle. But if you’re protecting a business with heavy activity, this use of AI may be moot.
- Retention Length: Video surveillance retention requirements can vary significantly based on local, state, and federal regulations. These laws dictate how long companies must store their video surveillance footage. For example, medical marijuana dispensaries in Ohio require 24/7 security video to be retained for a minimum of six months, and the footage must be made available to the licensing board upon request. The required length can be prolonged even further if a piece of footage is required for an ongoing investigation. Additionally, backing up your video footage (i.e., saving a copy of it in another area) is different from archiving it for long-term use. You’ll want to be sure that you select a storage system that helps you meet those requirements—more on that later.
Each point on this list affects how much storage capacity you need. More cameras mean more footage being generated, which means more video files. Additionally, a higher resolution and frame rate mean larger file sizes. Multiply this by the round-the-clock operation of surveillance cameras and the required retention length, and you’ll likely have more video data than you know what to do with.
Scoping Video Surveillance Storage: An Example
To illustrate how much footage you can expect to collect, it can be helpful to see an example of how a given business’s video surveillance may operate. Note that this example may not apply to you specifically. You should review your local area’s regulations and consult with an industry professional to make sure you are compliant.
Let’s say that you need to install surveillance cameras for a bank. Customers enter through the lobby and wait for the next available bank teller to assist them at a teller station. No items are put on display, only the exchange of paper and cash between the teller and the customer. Only authorized employees are allowed within the teller area. After customers complete their transactions, they walk back through the lobby area and exit via the building’s front entry.
As an estimate, let’s say you need at least 10 cameras around your building: one for the entrance; another for the lobby; eight more to cover the general back area, including the door to the teller terminals, the teller terminals themselves, the door to the safe, and inside of the safe; and, of course, one for the room where the surveillance equipment is housed. You may need more than 10 to cover the exterior of your building plus your ATM and drive through banking, but for the sake of an example, we’ll leave it at 10.
Now, suppose all your cameras record at 1080p resolution (1920 x 1080 px), 15 FPS, and a color depth of 14 bits (basically, how many colors the camera captures). For one 24 hour recording on one camera, you’re looking at 4.703 terabytes (TB). Over 30 days of storage, this can grow to 141.1TB. In other words, if the average person today needs a 2TB hard disk for their PC, it will take more than 70 PCs to hold all the information from just one camera.
How Cloud Storage Can Help Back Up Surveillance Footage
Backing up surveillance footage is essential for ensuring data security and accountability. It provides a reliable record of events, aids in investigations, and helps prevent wrongdoing by acting as a deterrent. But the right backup strategy is key to preserving your footage.
The 3-2-1 backup strategy is an accepted foundational structure that recommends keeping three copies of all important data (one primary copy and two backup copies) on two different media types (to diversify risk) and storing at least one copy off-site. With surveillance data utilizing high-capacity data storage systems, adhering to the 3-2-1 rule is important in order to access footage in case of an investigation. The 3-2-1 rule mitigates single points of failure, enhances data availability, and protects against corruption. By adhering to this rule, you increase the resilience of your surveillance footage, making it easier to recover even in unexpected events or disasters.
Having an on-site backup copy is a great start for the 3-2-1 backup strategy, but having an off-site backup is a key component in having a complete backup strategy. Having a backup copy in the cloud provides an easy to maintain, reliable off-site copy, safeguarding against a host of potential data losses including:
- Natural Disasters: If your business is harmed by a natural disaster, the devices you use for your primary storage or on-site backup may be damaged, resulting in a loss of data.
- Tampering and Theft: Even if someone doesn’t try to steal or manipulate your surveillance footage, an employee can still move, change, or delete files accidentally. You’ll need to safeguard footage with proper security protocols, such as authorization codes, data immutability, and encryption keys. These protocols may require constant, professional, and IT administration and maintenance that are often automatically built into the cloud.
- Lack of Backup and Archive Protocols: Unless your primary storage source uses specialized software to automatically save copies of your footage or move them to long-term storage, any of your data may be lost.
The cloud has transformed backup strategies and made it easy to ensure the integrity of large data sets, like surveillance footage. Here’s how the cloud helps achieve the 3-2-1 back strategy affordably:
- Scalability: With the cloud, your backup storage space is no longer limited to what servers you can afford. The cloud provider will continue to build and deploy new servers to keep up with customer demand, meaning you can simply rent out the storage space and pay for more as needed.
- Reliability: Most cloud providers share information on their durability and reliability and are heavily invested in building systems and processes to mitigate the impact of failures. Their systems are built to be fault-tolerant.
- Security: Cloud providers protect data you store with them with enterprise-grade security measures and offer features like access controls and encryption to allow users the ability to better protect their data.
- Affordability: Cloud storage helps you use your storage budgets effectively by not paying to provision and maintain physical off-site backup locations yourself.
- Disaster Recovery: If unexpected disasters occur, such as natural disasters, theft, or hardware failure, you’ll know exactly where your data lives in the cloud and how to restore it so you can get back up and running quickly.
- Compliance: By adhering to a set of standards and regulations cloud solutions meet compliance requirements to ensure data stored and managed in the cloud is protected and used responsibly.
Protect The Footage You Invested In to Protect Yourself
No matter the size, operation, or location of your business, it’s critical to remain compliant with all industry laws and regulations—especially when it comes to surveillance. Protect your business by partnering with a cloud provider that understands your unique business requirements, offering scalable, reliable, and secure services at a fraction of the cost compared with other platforms.
As a leading specialized cloud provider, Backblaze B2 Cloud Storage can secure your surveillance footage for both primary backup and long-term protection. B2 offers a range of security options—from encryption to Object Lock to Cloud Replication and access management controls—to help you protect your data and achieve industry compliance. Learn more about Backblaze B2 for surveillance data or contact our Sales Team today.
The post How Much Storage Do I Need to Back Up My Video Surveillance Footage? appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.
2024-03-05 The failed live migration case
Post Syndicated from Vasil Kolev original https://vasil.ludost.net/blog/?p=3474
There’s a purpose in everyone’s life. Some days, it seems like mine is to show people what not to do.
I’ve written this explanation to show my mistakes and that, hopefully, other people don’t (there’s no hope for me). What follows is most of my debugging process, and it could be helpful to other people to see it (and point out what is wrong with it).
This happens in a StorPool deployment for a customer who runs a public cloud service. We provide the shared storage via some drivers of our own, and the customer uses OpenNebula to control Linux/KVM hypervisors. It’s all integrated very nicely and is used for our internal clouds.
KVM VMs are a qemu process in the Linux userspace with multiple threads.
The case started with a customer complaining that after an update we did to the storage software, the live migrations of his VMs started failing (the VMs would fail to move but would continue working on the original host). The problem was narrowed down to VMs started before a specific date (when we did the update mentioned above), and initially, it seemed to be contained to VMs that had QEMU CPU set (i.e., the least performant one).
At this point, I asked – can’t they restart all such VMs? This CPU type is mainly contributing to global warming anyway.
The reply was, “Are you insane? These are 900 VMs. We’ll reboot them, but we really don’t want to do that now”.
Fair point.
Then, some further tests showed that any VMs, not just the ones with the QEMU CPU, were failing the migration. Finally, someone looked into the (not easy to find) logs of qemu and found the following:
2024-02-20T09:46:41.938285Z qemu-kvm-one: qemu_savevm_state_complete_precopy_non_iterable: bdrv_inactivate_all() failed (-1)
(seriously. Trying to trace anything via the logs in OpenNebula/libvirt/qemu feels like interrogating prisoners who don’t speak your language.)
Two mistakes above that would’ve saved a day or two – I should’ve looked into the issue immediately myself instead of relying on hearsay and building the wrong picture (based on assumptions) in my head. I did not expect that the (routine) update we did could have any such effect.
I specifically checked if the same problem existed in our labs and test environments, where we had done the same routine update, and it didn’t exist.
Now, this was weird. The only mention of the above error was in https://bugzilla.redhat.com/show_bug.cgi?id=2058982 when the storage device on the originating side was broken. This was not the case here.
My first step was to get permission to use one VM at the customer for tests, and after I had that, I ran strace on it while migrating.
What I was able to see in the thread that performed the migration was:
prctl(PR_SET_NAME, "live_migration")    = 0
…
sendmsg(99, {msg_name=NULL, msg_namelen=0, msg_iov=[{iov_base="..."..., iov_len=32768}], msg_iovlen=1, msg_controllen=0, msg_flags=0}, 0) = 32768
sendmsg(99, {msg_name=NULL, msg_namelen=0, msg_iov=[{iov_base="..."..., iov_len=32768}], msg_iovlen=1, msg_controllen=0, msg_flags=0}, 0) = 32768
write(2, "2024-02-15T07:00:23.057678Z ", 28) = 28
write(2, "qemu-kvm-one:", 13)           = 13
write(2, " ", 1)                        = 1
write(2, "qemu_savevm_state_complete_precopy_non_iterable: bdrv_inactivate_all() failed (-1)", 82) = 82
write(2, "\n", 1)                       = 1
futex(0x55586af89640, FUTEX_WAKE_PRIVATE, 1) = 1
sendmsg(20, {msg_name=NULL, msg_namelen=0, msg_iov=[{iov_base="{\"timestamp\": {\"seconds\": 1707980423, \"microseconds\": 57880}, \"event\": \"MIGRATION\", \"data\": {\"status\": \"failed\"}}\r\n", iov_len=115}], msg_iovlen=1, msg_controllen=0, msg_flags=0}, 0) = 115
futex(0x55586af89640, FUTEX_WAIT_PRIVATE, 2, NULL) = -1 EAGAIN (Resource temporarily unavailable)
sendmsg(20, {msg_name=NULL, msg_namelen=0, msg_iov=[{iov_base="{\"timestamp\": {\"seconds\": 1707980423, \"microseconds\": 58133}, \"event\": \"RESUME\"}\r\n", iov_len=82}], msg_iovlen=1, msg_controllen=0, msg_flags=0}, 0) = 82
Some digging showed that 99 was the file descriptor with the connection to the remote qemu. This was the memory transfer, followed almost immediately by writing out the error and nothing in between.
So, being somewhat lost, I looked up debug symbols for qemu to see if I could trace this further. The usual tooling told me there weren’t:
[root@somewhere str3]# gdb /usr/libexec/qemu-kvm
GNU gdb (GDB) Rocky Linux 8.2-20.el8.0.1
Copyright (C) 2018 Free Software Foundation, Inc.
License GPLv3+: GNU GPL version 3 or later <http://gnu.org/licenses/gpl.html>
This is free software: you are free to change and redistribute it.
There is NO WARRANTY, to the extent permitted by law.
Type "show copying" and "show warranty" for details.
This GDB was configured as "x86_64-redhat-linux-gnu".
Type "show configuration" for configuration details.
For bug reporting instructions, please see:
<http://www.gnu.org/software/gdb/bugs/>.
Find the GDB manual and other documentation resources online at:
    <http://www.gnu.org/software/gdb/documentation/>.

For help, type "help".
Type "apropos word" to search for commands related to "word"...
Reading symbols from /usr/libexec/qemu-kvm...Reading symbols from .gnu_debugdata for /usr/libexec/qemu-kvm...(no debugging symbols found)...done.
(no debugging symbols found)...done.
Missing separate debuginfos, use: yum debuginfo-install qemu-kvm-core-6.2.0-33.module+el8.8.0+1454+0b2cbfb8.x86_64
(gdb) quit

[root@somewhere str3]# yum debuginfo-install qemu-kvm-core-6.2.0-33.module+el8.8.0+1454+0b2cbfb8.x86_64
Repository storpool-contrib is listed more than once in the configuration
enabling epel-debuginfo repository
Extra Packages for Enterprise Linux 8 - x86_64 - Debug                                                                                                                                                                                            4.0 MB/s | 6.1 MB     00:01
Last metadata expiration check: 0:00:02 ago on Thu Feb 15 16:26:34 2024.
Could not find debuginfo package for the following installed packages: qemu-kvm-core-15:6.2.0-33.module+el8.8.0+1454+0b2cbfb8.x86_64
Could not find debugsource package for the following installed packages: qemu-kvm-core-15:6.2.0-33.module+el8.8.0+1454+0b2cbfb8.x86_64
Dependencies resolved.
Nothing to do.
Complete!
(I can already hear people saying, “You’re an idiot”; someone had to point that out to me)
Then, the colleague in communication with the customer said, “BTW, do you remember that at that time we did the other update, to migrate from one-type-of-volume-name to the-other-type-of-volume-name”? Of course, I didn’t. We ran the same migration in our lab, and the issue was reproduced immediately.
The mistake was that I did not collect all available information (or even most of it), still relying on assumptions.
I could deploy the latest qemu for AlmaLinux (almost the same as what the customer was using), download debug symbols, and start digging. Yay.
On strace, the issue looked the same – lots of sending to the socket and then just the error. So, I started digging with gdb by attaching, adding a breakpoint, continuing the process, and then running a live migration to see how the situation looked like at different points of the program. I had something like this primed and pasted when I ran gdb -p xxxx (some comments added to explain what these are):
set print pretty			# the usual gdb print is hard to read
set pagination off			# pagination is annoying in this regard, my terminal can scroll
handle SIGUSR1 nostop pass		# qemu uses SIGUSR1 a lot
break block/block-backend.c:253		# stop here
cont					# continue execution
bt full					# print me a full backtrace with local variables when stopped
It took some time to read through the relevant code and ensure there wasn’t something obvious (which took many wrong turns). The issue looked like that bdrv_inactivate_recurse() was trying to remove write permissions from the devices and was failing for some reason.
6523     /* Inactivate this node */
6524     if (bs->drv->bdrv_inactivate) {
6525         ret = bs->drv->bdrv_inactivate(bs);
6526         if (ret < 0) {
6527             return ret;
6528         }
6529     }
6530
6531     QLIST_FOREACH(parent, &bs->parents, next_parent) {
6532         if (parent->klass->inactivate) {
6533             ret = parent->klass->inactivate(parent);
6534             if (ret < 0) {
6535                 return ret;
6536             }
6537         }
6538     }
6539
6540     bdrv_get_cumulative_perm(bs, &cumulative_perms,
6541                              &cumulative_shared_perms);
6542     if (cumulative_perms & (BLK_PERM_WRITE | BLK_PERM_WRITE_UNCHANGED)) {
6543         /* Our inactive parents still need write access. Inactivation failed. */
6544         return -EPERM;
6545     }
This is the code in question, and in bdrv_get_cumulative_perms(), there were some devices that still had r/w set even after the stuff between lines 6531 and 6533 had passed:
bdrv_inactivate_recurse (bs=0x556e00221530) at ../block.c:6534
6534                if (ret < 0) {
(gdb)
6531        QLIST_FOREACH(parent, &bs->parents, next_parent) {
(gdb)
6540        bdrv_get_cumulative_perm(bs, &cumulative_perms,
(gdb)
6542        if (cumulative_perms & (BLK_PERM_WRITE | BLK_PERM_WRITE_UNCHANGED)) {
(gdb)
bdrv_inactivate_all () at ../block.c:6591
6591            if (ret < 0) {
(gdb)
6592                bdrv_next_cleanup(&it);
(gdb)
The inactivate() function above was in block/block-backend.c and looks like this:
 250 static int blk_root_inactivate(BdrvChild *child)
 251 {
 252     BlockBackend *blk = child->opaque;
 253
 254     if (blk->disable_perm) {
 255         return 0;
 256     }
 257
 258     if (!blk_can_inactivate(blk)) {
 259         return -EPERM;
 260     }
 261
 262     blk->disable_perm = true;
 263     if (blk->root) {
 264         bdrv_child_try_set_perm(blk->root, 0, BLK_PERM_ALL, &error_abort);
 265     }
 266
 267     return 0;
 268 }
and what was happening was:
258         if (!blk_can_inactivate(blk)) {
(gdb)
262         blk->disable_perm = true;
(gdb)
263         if (blk->root) {
(gdb)
264             bdrv_child_try_set_perm(blk->root, 0, BLK_PERM_ALL, &error_abort);
(gdb)
bdrv_inactivate_recurse (bs=0x556e00221530) at ../block.c:6534
So qemu is calling it, and that was all OK.
Here, a few times, I had missed what this was trying to do. Here’s bdrv_child_try_set_perm():
2517
2518 int bdrv_child_try_set_perm(BdrvChild *c, uint64_t perm, uint64_t shared,
2519                             Error **errp)
2520 {
2521     Error *local_err = NULL;
2522     Transaction *tran = tran_new();
2523     int ret;
2524
2525     bdrv_child_set_perm(c, perm, shared, tran);
2526
2527     ret = bdrv_refresh_perms(c->bs, &local_err);
2528
2529     tran_finalize(tran, ret);
2530
2531     if (ret < 0) {
2532         if ((perm & ~c->perm) || (c->shared_perm & ~shared)) {
2533             /* tighten permissions */
2534             error_propagate(errp, local_err);
2535         } else {
2536             /*
2537              * Our caller may intend to only loosen restrictions and
2538              * does not expect this function to fail.  Errors are not
2539              * fatal in such a case, so we can just hide them from our
2540              * caller.
2541              */
2542             error_free(local_err);
2543             ret = 0;
2544         }
2545     }
2546
2547     return ret;
2548 }
So that 0 being passed is “remove all permissions”, but at some time late in the day, you can’t see it…
And now, I break into that one and try to see what happens:
(gdb) n
2197        *s = (BdrvChildSetPermState) {
(gdb) print *(local_err)
No symbol "local_err" in current context.
(gdb)
No symbol "local_err" in current context.
(gdb) n
2203        c->perm = perm;
(gdb) print *(local_err)
No symbol "local_err" in current context.
(gdb) n
2204        c->shared_perm = shared;
(gdb) print *(local_err)
No symbol "local_err" in current context.
(gdb) n
2206        tran_add(tran, &bdrv_child_set_pem_drv, s);
(gdb) n
bdrv_child_try_set_perm (c=0x556e002e1730, perm=perm@entry=0, shared=shared@entry=31, errp=0x556dfeb99258 <error_abort>) at ../block.c:2527
2527        ret = bdrv_refresh_perms(c->bs, &local_err);
(gdb) print *(local_err)
Cannot access memory at address 0x0
(gdb) n
2529        tran_finalize(tran, ret);
(gdb) print *(local_err)
$1 = {
  msg = 0x7f25a4041b70 "Could not open '/var/lib/one//datastores/0/310/disk.0': No such file or directory",
  err_class = ERROR_CLASS_GENERIC_ERROR,
  src = 0x556dfe63ca2a "../util/osdep.c",
  func = 0x556dfe63cbc0 <__func__.26488> "qemu_open_internal",
  line = 359,
  hint = 0x0
}
(gdb) q
Now, I see it going through the function, and I’m trying to look at that local_err if there’s something in it. Finally, I get the actual error; it has happened somewhere and is not propagated – but qemu has tried opening a file, and that doesn’t exist.
Two things here:
– This file does exist (it’s a symlink to a symlink to a block device, and I can access it with the permissions of the process);
– Why isn’t this error logged or propagated? I should probably send a patch for that…
– This was not in what strace showed, so what the hell.
So, I break at util/osdep.c in qemu_open_internal(), to see what happens. I pass through that a few times, trying to see where that error comes from, because I still think there is no syscall there, and glibc is screwing with me. This goes to show that you shouldn’t debug when tired because glibc returning ENOENT on its own is a lot less likely than strace missing one syscall.
I’m going to leave out a lot of unsuccessful attempts and show you how I got to the next clue in one large gdb session (commends with #):
(gdb) break util/osdep.c:312
Breakpoint 1 at 0x556dfe2c5c71: file ../util/osdep.c, line 312.
(gdb) handle SIGUSR1 nostop pass
Signal        Stop      Print   Pass to program Description
SIGUSR1       No        Yes     Yes             User defined signal 1
(gdb) set print pretty
(gdb) set pagination off
(gdb) cont
Continuing.
[New Thread 0x7f259c9ba700 (LWP 1798462)]
[New Thread 0x7f259c1b9700 (LWP 1798463)]

Thread 5 "CPU 0/KVM" received signal SIGUSR1, User defined signal 1.

Thread 5 "CPU 0/KVM" received signal SIGUSR1, User defined signal 1.

Thread 5 "CPU 0/KVM" received signal SIGUSR1, User defined signal 1.
[Switching to Thread 0x7f259c1b9700 (LWP 1798463)]

Thread 8 "live_migration" hit Breakpoint 1, qemu_open_internal (name=name@entry=0x556e0021b241 "/var/lib/one//datastores/0/310/disk.0", flags=16384, mode=mode@entry=0, errp=errp@entry=0x7f259c1b85e0) at ../util/osdep.c:318
318         if (strstart(name, "/dev/fdset/", &fdset_id_str)) {
(gdb) bt full
… 				# nothing interesting in the backtrace
(gdb) disassemble
Dump of assembler code for function qemu_open_internal:
   0x0000556dfe2c5c40 <+0>:     push   %r15
   0x0000556dfe2c5c42 <+2>:     push   %r14
   0x0000556dfe2c5c44 <+4>:     mov    %rcx,%r14
   0x0000556dfe2c5c47 <+7>:     push   %r13
   0x0000556dfe2c5c49 <+9>:     mov    %edx,%r13d
   0x0000556dfe2c5c4c <+12>:    push   %r12
   0x0000556dfe2c5c4e <+14>:    mov    %esi,%r12d
   0x0000556dfe2c5c51 <+17>:    lea    0x376dad(%rip),%rsi        # 0x556dfe63ca05
   0x0000556dfe2c5c58 <+24>:    push   %rbp
   0x0000556dfe2c5c59 <+25>:    mov    %rdi,%rbp
   0x0000556dfe2c5c5c <+28>:    push   %rbx
   0x0000556dfe2c5c5d <+29>:    sub    $0x28,%rsp
   0x0000556dfe2c5c61 <+33>:    mov    %fs:0x28,%rax
   0x0000556dfe2c5c6a <+42>:    mov    %rax,0x18(%rsp)
   0x0000556dfe2c5c6f <+47>:    xor    %eax,%eax
=> 0x0000556dfe2c5c71 <+49>:    lea    0x10(%rsp),%rdx
   0x0000556dfe2c5c76 <+54>:    callq  0x556dfe2c6a30 <strstart>
   0x0000556dfe2c5c7b <+59>:    test   %eax,%eax
   0x0000556dfe2c5c7d <+61>:    je     0x556dfe2c5cd8 <qemu_open_internal+152>
   0x0000556dfe2c5c7f <+63>:    mov    0x10(%rsp),%rdi
   0x0000556dfe2c5c84 <+68>:    callq  0x556dfe2c79b0 <qemu_parse_fd>
   0x0000556dfe2c5c89 <+73>:    movslq %eax,%rdi
   0x0000556dfe2c5c8c <+76>:    mov    %rdi,%rbx
   0x0000556dfe2c5c8f <+79>:    cmp    $0xffffffffffffffff,%rdi
   0x0000556dfe2c5c93 <+83>:    je     0x556dfe2c5d7c <qemu_open_internal+316>
   0x0000556dfe2c5c99 <+89>:    mov    %r12d,%esi
   0x0000556dfe2c5c9c <+92>:    callq  0x556dfe101b60 <monitor_fdset_dup_fd_add>
   0x0000556dfe2c5ca1 <+97>:    mov    %eax,%ebx
   0x0000556dfe2c5ca3 <+99>:    cmp    $0xffffffff,%eax
   0x0000556dfe2c5ca6 <+102>:   je     0x556dfe2c5db3 <qemu_open_internal+371>
   0x0000556dfe2c5cac <+108>:   mov    0x18(%rsp),%rcx
   0x0000556dfe2c5cb1 <+113>:   xor    %fs:0x28,%rcx
   0x0000556dfe2c5cba <+122>:   mov    %ebx,%eax
   0x0000556dfe2c5cbc <+124>:   jne    0x556dfe2c5dd3 <qemu_open_internal+403>
   0x0000556dfe2c5cc2 <+130>:   add    $0x28,%rsp
   0x0000556dfe2c5cc6 <+134>:   pop    %rbx
   0x0000556dfe2c5cc7 <+135>:   pop    %rbp
   0x0000556dfe2c5cc8 <+136>:   pop    %r12
   0x0000556dfe2c5cca <+138>:   pop    %r13
   0x0000556dfe2c5ccc <+140>:   pop    %r14
   0x0000556dfe2c5cce <+142>:   pop    %r15
   0x0000556dfe2c5cd0 <+144>:   retq
   0x0000556dfe2c5cd1 <+145>:   nopl   0x0(%rax)
   0x0000556dfe2c5cd8 <+152>:   mov    %r12d,%esi
   0x0000556dfe2c5cdb <+155>:   mov    %r13d,%edx
   0x0000556dfe2c5cde <+158>:   mov    %rbp,%rdi
   0x0000556dfe2c5ce1 <+161>:   xor    %eax,%eax
   0x0000556dfe2c5ce3 <+163>:   or     $0x80000,%esi
   0x0000556dfe2c5ce9 <+169>:   callq  0x556dfdf0f190 <open64@plt>

…
I am not good at reading assembly, so if I’m doing this, I’m desperate (the colleague talking to the client was sitting next to me and asking why I was digging in the assembly). I see that it should call open64@plt, which looks like the syscall open to me.
I spend some time stepping instruction by instruction and trying to understand (and failing) what /usr/include/bits/fcntl2.h is doing with the macros there, but instruction by instruction I get to this:
(gdb) si
__libc_open64 (file=file@entry=0x556e0021b241 "/var/lib/one//datastores/0/310/disk.0", oflag=oflag@entry=540672) at ../sysdeps/unix/sysv/linux/open64.c:37
37      {
(gdb) si
0x00007f25d7a401d4      37      {
(gdb) si
0x00007f25d7a401d8      37      {
(gdb) disassemble
Dump of assembler code for function __libc_open64:
   0x00007f25d7a401d0 <+0>:     endbr64
   0x00007f25d7a401d4 <+4>:     sub    $0x68,%rsp
=> 0x00007f25d7a401d8 <+8>:     mov    %esi,%r10d
   0x00007f25d7a401db <+11>:    mov    %rdx,0x40(%rsp)
   0x00007f25d7a401e0 <+16>:    mov    %fs:0x28,%rax
   0x00007f25d7a401e9 <+25>:    mov    %rax,0x28(%rsp)
   0x00007f25d7a401ee <+30>:    xor    %eax,%eax
   0x00007f25d7a401f0 <+32>:    and    $0x40,%r10d
   0x00007f25d7a401f4 <+36>:    jne    0x7f25d7a40248 <__libc_open64+120>
   0x00007f25d7a401f6 <+38>:    mov    %esi,%eax
   0x00007f25d7a401f8 <+40>:    and    $0x410000,%eax
   0x00007f25d7a401fd <+45>:    cmp    $0x410000,%eax
   0x00007f25d7a40202 <+50>:    je     0x7f25d7a40248 <__libc_open64+120>
   0x00007f25d7a40204 <+52>:    mov    0x20d236(%rip),%eax        # 0x7f25d7c4d440 <__pthread_multiple_threads>
   0x00007f25d7a4020a <+58>:    test   %eax,%eax
   0x00007f25d7a4020c <+60>:    jne    0x7f25d7a40273 <__libc_open64+163>
   0x00007f25d7a4020e <+62>:    mov    %esi,%edx
   0x00007f25d7a40210 <+64>:    mov    $0x101,%eax
   0x00007f25d7a40215 <+69>:    mov    %rdi,%rsi
   0x00007f25d7a40218 <+72>:    mov    $0xffffff9c,%edi
   0x00007f25d7a4021d <+77>:    syscall
   0x00007f25d7a4021f <+79>:    cmp    $0xfffffffffffff000,%rax
   0x00007f25d7a40225 <+85>:    ja     0x7f25d7a402c8 <__libc_open64+248>
   0x00007f25d7a4022b <+91>:    mov    0x28(%rsp),%rcx
   0x00007f25d7a40230 <+96>:    xor    %fs:0x28,%rcx
   0x00007f25d7a40239 <+105>:   jne    0x7f25d7a402f1 <__libc_open64+289>
   0x00007f25d7a4023f <+111>:   add    $0x68,%rsp
And that, at 0x00007f25d7a4021d <+77>: is obviously the entry point to the kernel (the syscall). So…
(gdb) si
0x00007f25d7a40289      48        return SYSCALL_CANCEL (openat, AT_FDCWD, file, oflag | EXTRA_OPEN_FLAGS,
(gdb) si
0x00007f25d7a4028d      48        return SYSCALL_CANCEL (openat, AT_FDCWD, file, oflag | EXTRA_OPEN_FLAGS,
(gdb) si
0x00007f25d7a40290      48        return SYSCALL_CANCEL (openat, AT_FDCWD, file, oflag | EXTRA_OPEN_FLAGS,
(gdb) si
0x00007f25d7a40295      48        return SYSCALL_CANCEL (openat, AT_FDCWD, file, oflag | EXTRA_OPEN_FLAGS,
(gdb) si
0x00007f25d7a4029a      48        return SYSCALL_CANCEL (openat, AT_FDCWD, file, oflag | EXTRA_OPEN_FLAGS,
(gdb) si
0x00007f25d7a4029c      48        return SYSCALL_CANCEL (openat, AT_FDCWD, file, oflag | EXTRA_OPEN_FLAGS,
(gdb) si
0x00007f25d7a4029f      48        return SYSCALL_CANCEL (openat, AT_FDCWD, file, oflag | EXTRA_OPEN_FLAGS,
(gdb) si
0x00007f25d7a402a4      48        return SYSCALL_CANCEL (openat, AT_FDCWD, file, oflag | EXTRA_OPEN_FLAGS,
(gdb) si
0x00007f25d7a402a6      48        return SYSCALL_CANCEL (openat, AT_FDCWD, file, oflag | EXTRA_OPEN_FLAGS,
(gdb) disassemble
Dump of assembler code for function __libc_open64:
… 			# omitted
   0x00007f25d7a40285 <+181>:   mov    0xc(%rsp),%esi
   0x00007f25d7a40289 <+185>:   mov    (%rsp),%rdi
   0x00007f25d7a4028d <+189>:   mov    %eax,%r8d
   0x00007f25d7a40290 <+192>:   mov    0x8(%rsp),%r10d
   0x00007f25d7a40295 <+197>:   mov    $0x101,%eax
   0x00007f25d7a4029a <+202>:   mov    %esi,%edx
   0x00007f25d7a4029c <+204>:   mov    %rdi,%rsi
   0x00007f25d7a4029f <+207>:   mov    $0xffffff9c,%edi
   0x00007f25d7a402a4 <+212>:   syscall
=> 0x00007f25d7a402a6 <+214>:   cmp    $0xfffffffffffff000,%rax
   0x00007f25d7a402ac <+220>:   ja     0x7f25d7a402de <__libc_open64+270>
Maybe not the one I expected, but by stepping instruction by instruction, I obviously called a syscall here. So qemu asks the kernel about the file, and the kernel says it’s not there.
So for the hell of it I run strace -e trace=open,openat -p PIDFILE, and
[root@a8onekvm1 ~]# strace -f -p 1463232 -o dbg.open -s 255 -e trace=open,openat
strace: Process 1463232 attached with 6 threads
strace: Process 1832488 attached
strace: Process 1832489 attached
^Cstrace: Process 1463232 detached
strace: Process 1463236 detached
strace: Process 1463237 detached
strace: Process 1463240 detached
strace: Process 1463242 detached
strace: Process 1463245 detached

[root@a8onekvm1 ~]# grep open dbg.open
1832489 openat(AT_FDCWD, "/var/lib/one//datastores/0/310/disk.0", O_RDONLY|O_DIRECT|O_CLOEXEC) = -1 ENOENT (No such file or directory)
So, now strace sees it, but otherwise doesn’t?
Cue 5 minutes of me, yelling about strace betraying me, then checking that the file exists, writing a small C program to execute the exact same syscall with the permissions of the process, and (being late Friday afternoon and being tired) complaining to other people. And someone says, “this is most probably mount namespaces issue”.
And what do you know, it is:
[root@a8onekvm1 1463232]# nsenter -m -t 1463232 ls -l /var/lib/one//datastores/0/310/disk.0
lrwxrwxrwx 1 oneadmin oneadmin 28 Feb 16 11:02 /var/lib/one//datastores/0/310/disk.0 -> /dev/storpool-byid/fir.b.f2g
[root@a8onekvm1 1463232]# nsenter -m -t 1463232 ls -l /dev/storpool-byid
ls: cannot access '/dev/storpool-byid': No such file or directory
Sooo… what we have done is replace the symlink from pointing to /dev/storpool/XXX to /dev/storpool-byid/YYY. The namespace for qemu doesn’t have the second directory, it was not in use when the process was started, and we have just screwed it by moving the symlink.
So, happy with that, on Monday I wrote a lousy script to recreate the links, which one of my colleagues made into a good script that people won’t be ashamed to show, for example, replacing
virsh dumpxml one-316 |grep 'source dev.*datastores' | cut -d ' ' -f 2
with
xmlstarlet sel -t -m '//devices/disk/source' -v '@dev' -n "${DOMXML}" 2>/dev/null
Then, we apply this to the live environment to one VM, and happily tell the customer to try a live migration.
It fails with the same error.
(cut some time for swearing at the world and all broken software)
So I’m back to square one, as I try strace-ing the process in the live environment with -e trace=open,openat, and there is no such call. I also tried ltrace, but the only difference was that it was slower and didn’t show anything more.
Then, a colleague says, “You know, these debuginfo packages should exist, they’re not that old”, goes looking in the mirrors, and FINDS THEM. For some reason, google doesn’t index that part, and I could not find them the lazy way.
Here’s the obvious error that you should look for yourself. It would’ve been even easier if I logged in to the local mirror we have for Rocky Linux and ran a find for myself.
Armed with debug symbols, I get the test VM again, attach to it, add a breakpoint at qemu_internal_open(), and nothing happens. It doesn’t get hit. It looks like strace wasn’t lying here.
I go back to the blk_root_inactivate() function and I notice:
Thread 8 "live_migration" hit Breakpoint 1, blk_root_inactivate (child=0x55586bf47c00) at ../block/block-backend.c:252
252         BlockBackend *blk = child->opaque;
(gdb) bt
#0  blk_root_inactivate (child=0x55586bf47c00) at ../block/block-backend.c:252
#1  0x000055586a5e8162 in bdrv_inactivate_recurse (bs=0x55586b297760) at ../block.c:6533
#2  0x000055586a5e963f in bdrv_inactivate_all () at ../block.c:6590
#3  0x000055586a37b535 in qemu_savevm_state_complete_precopy_non_iterable (f=0x55586c05d500, in_postcopy=<optimized out>, inactivate_disks=</optimized><optimized out>) at ../migration/savevm.c:1441
#4  0x000055586a37b622 in qemu_savevm_state_complete_precopy (f=0x55586c05d500, iterable_only=iterable_only@entry=false, inactivate_disks=inactivate_disks@entry=true) at ../migration/savevm.c:1493
#5  0x000055586a374236 in migration_completion (s=0x55586b207000) at ../migration/migration.c:3260
#6  migration_iteration_run (s=0x55586b207000) at ../migration/migration.c:3672
#7  migration_thread (opaque=0x55586b207000) at ../migration/migration.c:3908
#8  0x000055586a6d9dc4 in qemu_thread_start (args=0x55586c0ee6c0) at ../util/qemu-thread-posix.c:585
#9  0x00007f4a951d11ca in start_thread () from target:/lib64/libpthread.so.0
#10 0x00007f4a94e3de73 in clone () from target:/lib64/libc.so.6
(gdb) n
254         if (blk->disable_perm) {
(gdb) n
bdrv_inactivate_recurse (bs=0x55586b297760) at ../block.c:6534
blk->disable_perm is already set, so it looks like in this version of qemu (a bit older than what I initially used), when the live migration fails, this flag doesn’t get reset. I made a diff between the two versions, and that part has enough changes to warrant this idea. So, VMs that didn’t fail the migration would be fine.
Now, what about this one and a few more? They seem to be in a corrupt state. I read a bit more code, then bite the bullet and change the variable live:
Thread 7 "live_migration" hit Breakpoint 1, blk_root_inactivate (child=0x55586bf47c00) at ../block/block-backend.c:254
254         if (blk->disable_perm) {
(gdb) bt
#0  blk_root_inactivate (child=0x55586bf47c00) at ../block/block-backend.c:254
#1  0x000055586a5e8162 in bdrv_inactivate_recurse (bs=0x55586b297760) at ../block.c:6533
#2  0x000055586a5e963f in bdrv_inactivate_all () at ../block.c:6590
#3  0x000055586a37b535 in qemu_savevm_state_complete_precopy_non_iterable (f=0x55586c05d500, in_postcopy=</optimized><optimized out>, inactivate_disks=</optimized><optimized out>) at ../migration/savevm.c:1441
#4  0x000055586a37b622 in qemu_savevm_state_complete_precopy (f=0x55586c05d500, iterable_only=iterable_only@entry=false, inactivate_disks=inactivate_disks@entry=true) at ../migration/savevm.c:1493
#5  0x000055586a374236 in migration_completion (s=0x55586b207000) at ../migration/migration.c:3260
#6  migration_iteration_run (s=0x55586b207000) at ../migration/migration.c:3672
#7  migration_thread (opaque=0x55586b207000) at ../migration/migration.c:3908
#8  0x000055586a6d9dc4 in qemu_thread_start (args=0x55586c2325e0) at ../util/qemu-thread-posix.c:585
#9  0x00007f4a951d11ca in start_thread () from target:/lib64/libpthread.so.0
#10 0x00007f4a94e3de73 in clone () from target:/lib64/libc.so.6
(gdb) print ( (BlockBackend *) (child->opaque))->disable_perm
$1 = true
(gdb) print ( (BlockBackend *) (child->opaque))->perm
$2 = 3
(gdb) set: variable ( (BlockBackend *) (child->opaque))->disable_perm = false
No symbol "false" in current context.	# arghhhh
(gdb) set variable ( (BlockBackend *) (child->opaque))->disable_perm = 0
(gdb) cont
Continuing.

Thread 7 "live_migration" hit Breakpoint 1, blk_root_inactivate (child=0x55586bf51850) at ../block/block-backend.c:254
254         if (blk->disable_perm) {
(gdb) print ( (BlockBackend *) (child->opaque))->disable_perm
$3 = false
(gdb) print ( (BlockBackend *) (child->opaque))->perm
$4 = 1
(gdb) cont
Continuing.
[Thread 0x7f4999ffb700 (LWP 144024) exited]
[Thread 0x7f499a7fc700 (LWP 144025) exited]

Thread 1 "qemu-kvm-one" received signal SIGTERM, Terminated.	# oops?
[Switching to Thread 0x7f4a985a6e40 (LWP 3460894)]
0x00007f4a94f28036 in ppoll () from target:/lib64/libc.so.6
(gdb) q
(imagine this being done live and as quickly as possible, as the VM is hanging. You also see two devices, OpenNebula adds a context image to all VMs, and it’s a CD-ROM device that the migration didn’t get to corrupt)
Then I see SIGTERM and think, “crap, I killed it”. Then I look at the logs, and it has actually migrated successfully.
So, finally, with some pointers (“the command in gdb is command” 🙂 ) I write the following:
set print pretty
set pagination off
handle SIGUSR1 nostop pass
handle SIGTERM nostop pass
break block/block-backend.c:253
commands
print ( (BlockBackend *) (child->opaque))->disable_perm
print ( (BlockBackend *) (child->opaque))->perm
set variable ( (BlockBackend *) (child->opaque))->disable_perm = 0
cont
end
cont
and it works like a charm on the 10-or-something VMs with a corrupt state.
A list of errors and lessons learned:
– Don’t assume that because there’s something not right, it’s the cause of the problem you’re looking at (QEMU processor for the VMs);
– Collect all relevant information (and maybe even irrelevant) – I keep telling people that it’s easier to work with too much information than with not enough. I should listen to myself one of these days;
– strace can hide syscalls and shouldn’t be fully trusted;
– If you’re searching for debuginfo (or anything like that), do your legwork, and don’t trust a single search engine;
– testing the wrong software version can reveal only a part of the problem (or a different one).
How to access AWS resources from Microsoft Entra ID tenants using AWS Security Token Service
Post Syndicated from Vasanth Selvaraj original https://aws.amazon.com/blogs/security/how-to-access-aws-resources-from-microsoft-entra-id-tenants-using-aws-security-token-service/
Use of long-term access keys for authentication between cloud resources increases the risk of key exposure and unauthorized secrets reuse. Amazon Web Services (AWS) has developed a solution to enable customers to securely authenticate Azure resources with AWS resources using short-lived tokens to reduce risks to secure authentication.
In this post, we guide you through the configuration of AWS Identity and Access Management (IAM) OpenID Connect (OIDC) identity provider to establish trust with a Microsoft Entra ID tenant. By following the steps outlined in this post, you will enable a Microsoft Azure hosted resources to use an IAM role, with privileges, to access your AWS resources.
Solution overview
In this solution, we show you how to obtain temporary credentials in IAM. The solution uses AWS Security Token Service (AWS STS) in conjunction with Azure managed identities and Azure App Registration. This method provides a more secure and efficient way to bridge Azure and AWS clouds, providing seamless integration without compromising secure authentication and authorization standards.
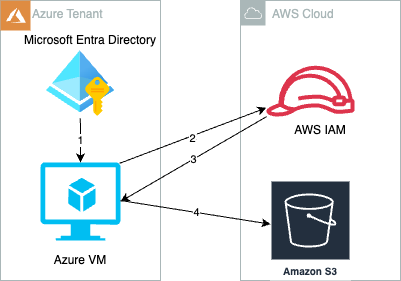
Figure 1: Azure cloud resources access AWS resources with temporary security credentials
As shown in Figure 1, the process is as follows:
- Create and attach an Azure managed identity to an Azure virtual machine (VM).
- Azure VM gets an Azure access token from the managed identity and sends it to AWS STS to retrieve temporary security credentials.
- An IAM role created with a valid Azure tenant audience and subject validates that the claim is sourced from a trusted entity and sends temporary security credentials to the requesting Azure VM.
- Azure VM accesses AWS resources using the AWS STS provided temporary security credentials.
Prerequisites
You must have the following before you begin:
- An AWS account.
- An Azure account subscription.
- In your Azure account, ensure there’s an existing managed identity or create a new one for testing this solution. More information can be found in Configure managed identities for Azure resources on a VM using the Azure portal.
- Create a VM instance in Azure and attach the managed identity that you created in Step 3.
- Install jq, boto3, and AWS Command Line Interface (AWS CLI) version 2 on an Azure VM for testing.
Implementation
To prepare the authentication process with Microsoft Entra ID, an enterprise application must be created in Microsoft Entra ID. This serves as a sign-in endpoint and provides the necessary user identity information through OIDC access tokens to the identity provider (IdP) of the target AWS account.
Note: You can get short term credentials by providing access tokens from managed identities or enterprise applications. This post covers the enterprise application use case.
Register a new application in Azure
- In the Azure portal, select Microsoft Entra ID.
- Select App registrations.
- Select New registration.
- Enter a name for your application and then select an option in Supported account types (in this example, we chose Accounts in this Organization directory only). Leave the other options as is. Then choose Register.

Figure 2: Register an application in the Azure portal

Configure the application ID URI
- In the Azure portal, select Microsoft Entra ID.
- Select App registrations.
- On the App registrations page, select All applications and choose the newly registered application.
- On the newly registered application’s overview page, choose Application ID URI and then select Add.
- On the Edit application ID URI page, enter the value of the URI, which looks like
urn://<name of the application> or api://<name of the application>. - The application ID URI will be used later as the audience in the identity provider(idP) section of AWS.

Figure 3: Configure the application ID URI
- Open the newly registered application’s overview page.
- In the navigation pane, under Manage, choose App roles.
- Select Create app role and then enter a Display name and for Allowed member types, select Both (Users/Groups + Applications).
- For Description, enter a description.
- Select Do you want to enable this app role? And then choose Apply.

Figure 4: Create and enable an application role
- Assign a managed identity—as created in Step 4 of the prerequisites—to the new application role. This operation can only be done by either using the Azure Cloud Shell or running scripts locally by installing the latest version of the Microsoft Graph PowerShell SDK. (For more information about assigning managed identities to application roles using PowerShell, see Azure documentation.)
You must have the following information:
- ObjectID: To find the managed identity’s Object (Principal) ID, go to the Managed Identities page, select the identity name, and then select Overview.

Figure 5: Find the ObjectID of the managed identity
- ID: To find the ID of the application role, go to App registrations, select the application name, and then select App roles.

Figure 6: Find the ID of the application role
- PrincipalID: Same as ObjectID, which is the managed identity’s Object (Principal) ID.
- ResourceID: The ObjectID of the resource service principal, which you can find by going to the Enterprise applications page and selection the application. Select Overview and then Properties to find the ObjectID.

Figure 7: Find the ResourceID
- ObjectID: To find the managed identity’s Object (Principal) ID, go to the Managed Identities page, select the identity name, and then select Overview.
- With the resource IDs, you can now use Azure Cloud Shell and run the following script in PowerShell terminal with New-AzureADServiceAppRoleAssignment. Replace the variables with the resource IDs.


Configure AWS
- In the AWS Management Console for IAM, create an IAM Identity Provider.
- In the left navigation pane, select Identity providers and then choose Add an identity provider.
- For Provider type, choose OpenID Connect.
- For Provider URL, enter
https://sts.windows.net/<Microsoft Entra Tenant ID>. Replace<Microsoft Entra Tenant ID>with your Tenant ID from Azure. This allows only identities from your Azure tenant to access your AWS resources. - For Audience use the
client_idof the Azure managed identity or the application ID URI from enterprise applications.- For Audience, enter the application ID URI that you configured on step 5 of Configure the application ID URI. If you have additional client IDs (also known as audiences) for this IdP, you can add them to the provider detail page later.
- You can also use different audiences in the role trust policy in the next step to limit the roles that specific audiences can assume. To do so, you must provide a
StringEqualscondition in the trust policy of the IAM role.

Figure 8: Adding an audience (client ID)
- Using an OIDC principal without a condition can be overly permissive. To make sure that only the intended identities assume the role, provide an audience (
aud) and subject (sub) as conditions in the role trust policy for this IAM role.sts.windows.net/<Microsoft Entra Tenant ID>/:subrepresents the identity of your Azure workload that limits access to the specific Azure identity that can assume this role from the Azure tenant. See the following example for conditions.- Replace
<Microsoft Entra Tenant ID>with your tenant ID from Azure. - Replace
<Application ID URI>with your audience value configured in the previous step. - Replace
<Managed Identity’s object (Principal) ID>with your ObjectID captured in the first bullet of Step 12 of Configure the application ID URI.
- Replace

Test the access
To test the access, you’ll assign a user assigned managed identity to an existing VM.
- Sign in to the Azure portal.
- Navigate to the desired VM and select Identity, User assigned, and then choose Add.

Figure 9: Assigning a User assigned Identity
- Select the managed identity created as part of prerequisite and then choose Add.

Figure 10: Add a user assigned managed identity
- In AWS, we used
credential_processin a separate AWS Config profile to dynamically and programmatically retrieve AWS temporary credentials. The credential process calls a bash script that retrieves an access token from Azure and uses the token to obtain temporary credentials from AWS STS. For the syntax and operating system requirements, see Source credentials with an external process. For this post, we created a custom profile calledDevTeam-S3ReadOnlyAccess, as shown in the config file:To use different settings, you can create and reference additional profiles.
- For this example,
credentials_processinvokes the script/opt/bin/credentials.sh. Replace<111122223333>with your own account ID. - After you configure the AWS Config CLI file for the
credential_processscript, verify the setup by accessing AWS resources from Azure VM.- Use AWS CLI to run the following command. You should see list of Amazon Simple Storage Service (Amazon S3) buckets from your account.
- Using AWS SDK for Python to run
s3AccessFromAzure.py. You should see a list of S3 buckets from your account. This example also demonstrates specifying a profile to use for credential purposes.


Note: The AWS CLI doesn’t cache external process credentials; instead, the AWS CLI calls the
credential_processfor every CLI request, which creates a new role session. If you use AWS SDKs, the credentials are cached and reused until they expire.
We used Azure VM as an example to access AWS resources, but a similar approach can be used for any compute resources in Azure that are capable of issuing Azure credentials.
Clean up
If you don’t need the resources that you created for this walkthrough, delete them to avoid future charges for the deployed resources:
- Delete the VM instance, managed identity, and enterprise applications created in Azure.
- Delete the resources that you provisioned on AWS to test the solution.
Conclusion
In this post, we showed you how to securely access AWS resources from Azure workloads using an IAM role assumed with one-time, short-term credentials. By using this solution, your Azure workloads will request temporary security credentials and remove the need for long-term AWS credentials or other secrets usage that are less secure methods of authentication.
Use the following resources to help you get started with AWS IAM federation:
- Identity federation in AWS
- About web identity federation
- AWS Identity and Access Management Forums
- How to use managed identities for Azure resources on an Azure VM to acquire an access token
If you have feedback about this post, submit comments in the Comments section below.
Home Assistant is Dropping 2024.3 release – today ;)
Post Syndicated from BeardedTinker original https://www.youtube.com/watch?v=1ggyF8pM4EE
Free data transfer out to internet when moving out of AWS
Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/free-data-transfer-out-to-internet-when-moving-out-of-aws/
You told us one of the primary reasons to adopt Amazon Web Services (AWS) is the broad choice of services we offer, enabling you to innovate, build, deploy, and monitor your workloads. AWS has continuously expanded its services to support virtually any cloud workload. It now offers over 200 fully featured services for compute, storage, databases, networking, analytics, machine learning (ML) and artificial intelligence (AI), and many more. For example, Amazon Elastic Compute Cloud (Amazon EC2) offers over 750 generally available instances—more than any other major cloud provider—and you can choose from numerous relational, analytics, key-value, document, or graph databases.
We believe this choice must include the one to migrate your data to another cloud provider or on-premises. That’s why, starting today, we’re waiving data transfer out to the internet (DTO) charges when you want to move outside of AWS.
Over 90 percent of our customers already incur no data transfer expenses out of AWS because we provide 100 gigabytes per month free from AWS Regions to the internet. This includes traffic from Amazon EC2, Amazon Simple Storage Service (Amazon S3), Application Load Balancer, among others. In addition, we offer one terabyte of free data transfer out of Amazon CloudFront every month.
If you need more than 100 gigabytes of data transfer out per month while transitioning, you can contact AWS Support to ask for free DTO rates for the additional data. It’s necessary to go through support because you make hundreds of millions of data transfers each day, and we generally do not know if the data transferred out to the internet is a normal part of your business or a one-time transfer as part of a switch to another cloud provider or on premises.
We will review requests at the AWS account level. Once approved, we will provide credits for the data being migrated. We don’t require you to close your account or change your relationship with AWS in any way. You’re welcome to come back at any time. We will, of course, apply additional scrutiny if the same AWS account applies multiple times for free DTO.
We believe in customer choice, including the choice to move your data out of AWS. The waiver on data transfer out to the internet charges also follows the direction set by the European Data Act and is available to all AWS customers around the world and from any AWS Region.
Freedom of choice is not limited to data transfer rates. AWS also supports Fair Software Licensing Principles, which make it easy to use software with other IT providers of your choice. You can read this blog post for more details.
You can check the FAQ for more information, or you can contact AWS Customer Support to request credits for DTO while switching.
But I sincerely hope you will not.
Secure your unprotected assets with Security Center: quick view for CISOs
Post Syndicated from Alexandra Moraru original https://blog.cloudflare.com/security-insights-quick-ciso-view
We understand that one of the significant hurdles faced by our customers, especially larger organizations, is obtaining a clear view of the deployment of Cloudflare services throughout their vast and complex infrastructures. The question isn’t just whether Cloudflare is deployed, but whether it’s fully optimized across every asset and service. Addressing this challenge head-on, we’re rolling out a new feature set designed to provide better visibility and control over your security posture.
The problem we are addressing
The core problem we’re tackling is the growing complexity of cyber threats and the expanding attack surface, which complicates maintaining a strong security posture for our customers.
It’s not uncommon for organizations to deploy a variety of security solutions, including ours, without fully optimizing and implementing their configurations. This results in a false sense of security, underutilized investments and, more critically, exposed vulnerabilities. Our customers frequently express concerns about not having a clear picture of their security posture across their entire infrastructure, uncertain if critical assets are adequately protected or if specific Cloudflare security features could be better leveraged.
We want to bring users comprehensive visibility into their security configurations and the state of their deployments across Cloudflare’s suite of products. By providing actionable insights into underconfigured areas, unassigned resources, or unutilized features, we aim to close the security gaps and enhance the overall defense mechanisms of our customers’ digital ecosystems. This improvement is not just about leveraging technology but about promoting a culture of proactive security management, where every piece of the digital infrastructure is consistently and optimally protected.
How we’re solving this inside Security Center
More than two years ago, we took on the mission to consolidate our extensive suite of security products, security expertise, and our unique insights into Internet threats into one comprehensive solution — the Cloudflare Security Center. Launched with the vision to simplify attack surface management and make advanced security intelligence actionable for organizations of all sizes, Security Center has since become the one-stop quick view to evaluate your security posture.
Today, we build on this foundation to address a pain point for many of our large customers: ensuring complete Cloudflare protection across their entire digital infrastructure.
Our latest update in the Security Center focuses on delivering detailed insights into Cloudflare’s deployment status across your digital assets. This encompasses identifying applications where critical services like WAF, Access, and other security protection tools might not be fully configured or optimized, thereby weakening your security posture.
In addition to these insights, we are introducing a quick view within Security Center Insights, designed to offer CISOs and security teams a quick and comprehensive view of their current Cloudflare product configurations at any given moment, along with recommendations for enhancements, under the Security optimization snapshot on the dashboard.
Leveraging these new insights, Cloudflare users can now take proactive steps to close any gaps in their security framework. By offering a granular view of where specific Cloudflare services can be better utilized, we’re not just solving a visibility problem — we’re delivering actionable security intelligence. This means decisions can be made swiftly, ensuring that your defenses not only keep pace with, but stay ahead of, potential threats.
For instance, we’ll highlight if WAF is deployed on only a portion of your zones, where Email Security could be leveraged, or if certain assets are unprotected by Access controls. We’re also making it easier for you to see if you are missing any critical setup like Page Shield, ensuring the product is configured, so you are not just one step closer to becoming compliant with standards like PCI DSS, but are also protected against evolving threats. We are outlining newly discovered API endpoints that require your attention as well.
Finally, users can now export their Security Insights using our public API, and will soon be able to do the same directly from the Cloudflare Dashboard, with a simple click of a button!
Accessing Security Center Insights
Security Center Insights is available to all Cloudflare dashboard users that are Administrators of their Cloudflare account.
Regardless of the size or scope of your deployment, our goal is to empower every user with the tools needed to achieve a robust security posture, which they can continuously influence by improving existing configurations, adding new solutions, and discovering new vulnerabilities.
Future Security Center roadmap
We’re constantly adding other relevant security insights to help improve your security posture, covering exposed infrastructure, insecure configurations, optimisations, new products, and more, including the ability to easily export these for reporting purposes. Moreover, stay tuned for a completely new reporting platform that will automatically deliver curated and contextualized security insights directly into your inbox — showcasing the power of Cloudflare’s security portfolio. The periodic reports will be complemented by a personalized interactive in-dashboard reporting experience.
Check out your security insights under your account’s Security Center now and take action to improve your security posture with Cloudflare!
If you would like to join us in building the Security Center or other exciting Cloudflare products, see our open positions and learn more about life@Cloudflare.