Tag Archives: artificial intelligence

Stronger together: Highlights from RSA Conference 2023

Post Syndicated from Anne Grahn original https://aws.amazon.com/blogs/security/stronger-together-highlights-from-rsa-conference-2023/
Golden Gate bridge

RSA Conference 2023 brought thousands of cybersecurity professionals to the Moscone Center in San Francisco, California from April 24 through 27.

The keynote lineup was eclectic, with more than 30 presentations across two stages featuring speakers ranging from renowned theoretical physicist and futurist Dr. Michio Kaku to Grammy-winning musician Chris Stapleton. Topics aligned with this year’s conference theme, “Stronger Together,” and focused on actions that can be taken by everyone, from the C-suite to those of us on the front lines of security, to strengthen collaboration, establish new best practices, and make our defenses more diverse and effective.

With over 400 sessions and 500 exhibitors discussing the latest trends and technologies, it’s impossible to recap every highlight. Now that the dust has settled and we’ve had time to reflect, here’s a glimpse of what caught our attention.

Noteworthy announcements

Hundreds of companies — including Amazon Web Services (AWS) — made new product and service announcements during the conference.

We announced three new capabilities for our Amazon GuardDuty threat detection service to help customers secure container, database, and serverless workloads. These include GuardDuty Elastic Kubernetes Service (EKS) Runtime Monitoring, GuardDuty RDS Protection for data stored in Amazon Aurora, and GuardDuty Lambda Protection for serverless applications. The new capabilities are designed to provide actionable, contextual, and timely security findings with resource-specific details.

Artificial intelligence

It was hard to find a single keynote, session, or conversation that didn’t touch on the impact of artificial intelligence (AI).

In “AI: Law, Policy and Common Sense Suggestions on How to Stay Out of Trouble,” privacy and gaming attorney Behnam Dayanim highlighted ambiguity around the definition of AI. Referencing a quote from University of Washington School of Law’s Ryan Calo, Dayanim pointed out that AI may be best described as “…a set of techniques aimed at approximating some aspect of cognition,” and should therefore be thought of differently than a discrete “thing” or industry sector.

Dayanim noted examples of skepticism around the benefits of AI. A recent Monmouth University poll, for example, found that 73% of Americans believe AI will make jobs less available and harm the economy, and a surprising 55% believe AI may one day threaten humanity’s existence.

Equally skeptical, he noted, is a joint statement made by the Federal Trade Commission (FTC) and three other federal agencies during the conference reminding the public that enforcement authority applies to AI. The statement takes a pessimistic view, saying that AI is “…often advertised as providing insights and breakthroughs, increasing efficiencies and cost-savings, and modernizing existing practices,” but has the potential to produce negative outcomes.

Dayanim covered existing and upcoming legal frameworks around the world that are aimed at addressing AI-related risks related to intellectual property (IP), misinformation, and bias, and how organizations can design AI governance mechanisms to promote fairness, competence, transparency, and accountability.

Many other discussions focused on the immense potential of AI to automate and improve security practices. RSA Security CEO Rohit Ghai explored the intersection of progress in AI with human identity in his keynote. “Access management and identity management are now table stakes features”, he said. In the AI era, we need an identity security solution that will secure the entire identity lifecycle—not just access. To be successful, he believes, the next generation of identity technology needs to be powered by AI, open and integrated at the data layer, and pursue a security-first approach. “Without good AI,” he said, “zero trust has zero chance.”

Mark Ryland, director at the Office of the CISO at AWS, spoke with Infosecurity about improving threat detection with generative AI.

“We’re very focused on meaningful data and minimizing false positives. And the only way to do that effectively is with machine learning (ML), so that’s been a core part of our security services,” he noted.

We recently announced several new innovations—including Amazon Bedrock, the Amazon Titan foundation model, the general availability of Amazon Elastic Compute Cloud (Amazon EC2) Trn1n instances powered by AWS Trainium, Amazon EC2 Inf2 instances powered by AWS Inferentia2, and the general availability of Amazon CodeWhisperer—that will make it practical for customers to use generative AI in their businesses.

“Machine learning and artificial intelligence will add a critical layer of automation to cloud security. AI/ML will help augment developers’ workstreams, helping them create more reliable code and drive continuous security improvement. — CJ Moses, CISO and VP of security engineering at AWS

The human element

Dozens of sessions focused on the human element of security, with topics ranging from the psychology of DevSecOps to the NIST Phish Scale. In “How to Create a Breach-Deterrent Culture of Cybersecurity, from Board Down,” Andrzej Cetnarski, founder, chairman, and CEO of Cyber Nation Central and Marcus Sachs, deputy director for research at Auburn University, made a data-driven case for CEOs, boards, and business leaders to set a tone of security in their organizations, so they can address “cyber insecure behaviors that lead to social engineering” and keep up with the pace of cybercrime.

Lisa Plaggemier, executive director of the National Cybersecurity Alliance, and Jenny Brinkley, director of Amazon Security, stressed the importance of compelling security awareness training in “Engagement Through Entertainment: How To Make Security Behaviors Stick.” Education is critical to building a strong security posture, but as Plaggemier and Brinkley pointed out, we’re “living through an epidemic of boringness” in cybersecurity training.

According to a recent report, just 28% of employees say security awareness training is engaging, and only 36% say they pay full attention during such training.

Citing a United Airlines preflight safety video and Amazon’s Protect and Connect public service announcement (PSA) as examples, they emphasized the need to make emotional connections with users through humor and unexpected elements in order to create memorable training that drives behavioral change.

Plaggemeier and Brinkley detailed five actionable steps for security teams to improve their awareness training:

  • Brainstorm with staff throughout the company (not just the security people)
  • Find ideas and inspiration from everywhere else (TV episodes, movies… anywhere but existing security training)
  • Be relatable, and include insights that are relevant to your company and teams
  • Start small; you don’t need a large budget to add interest to your training
  • Don’t let naysayers deter you — change often prompts resistance
“You’ve got to make people care. And so you’ve got to find out what their personal motivators are, and how to develop the type of content that can make them care to click through the training and…remember things as they’re walking through an office.” — Jenny Brinkley, director of Amazon Security

Cloud security

Cloud security was another popular topic. In “Architecting Security for Regulated Workloads in Hybrid Cloud,” Mark Buckwell, cloud security architect at IBM, discussed the architectural thinking practices—including zero trust—required to integrate security and compliance into regulated workloads in a hybrid cloud environment.

Mitiga co-founder and CTO Ofer Maor told real-world stories of SaaS attacks and incident response in “It’s Getting Real & Hitting the Fan 2023 Edition.”

Maor highlighted common tactics focused on identity theft, including MFA push fatigue, phishing, business email compromise, and adversary-in-the middle attacks. After detailing techniques that are used to establish persistence in SaaS environments and deliver ransomware, Maor emphasized the importance of forensic investigation and threat hunting to gaining the knowledge needed to reduce the impact of SaaS security incidents.

Sarah Currey, security practice manager, and Anna McAbee, senior solutions architect at AWS, provided complementary guidance in “Top 10 Ways to Evolve Cloud Native Incident Response Maturity.” Currey and McAbee highlighted best practices for addressing incident response (IR) challenges in the cloud — no matter who your provider is:

  1. Define roles and responsibilities in your IR plan
  2. Train staff on AWS (or your provider)
  3. Develop cloud incident response playbooks
  4. Develop account structure and tagging strategy
  5. Run simulations (red team, purple team, tabletop)
  6. Prepare access
  7. Select and set up logs
  8. Enable managed detection services in all available AWS Regions
  9. Determine containment strategy for resource types
  10. Develop cloud forensics capabilities

Speaking to BizTech, Clarke Rodgers, director of enterprise strategy at AWS, noted that tools and services such as Amazon GuardDuty and AWS Key Management Service (AWS KMS) are available to help advance security in the cloud. When organizations take advantage of these services and use partners to augment security programs, they can gain the confidence they need to take more risks, and accelerate digital transformation and product development.

Security takes a village

There are more highlights than we can mention on a variety of other topics, including post-quantum cryptography, data privacy, and diversity, equity, and inclusion. We’ve barely scratched the surface of RSA Conference 2023. If there is one key takeaway, it is that no single organization or individual can address cybersecurity challenges alone. By working together and sharing best practices as an industry, we can develop more effective security solutions and stay ahead of emerging threats.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Anne Grahn

Anne Grahn

Anne is a Senior Worldwide Security GTM Specialist at AWS based in Chicago. She has more than a decade of experience in the security industry, and focuses on effectively communicating cybersecurity risk. She maintains a Certified Information Systems Security Professional (CISSP) certification.

Danielle Ruderman

Danielle Ruderman

Danielle is a Senior Manager for the AWS Worldwide Security Specialist Organization, where she leads a team that enables global CISOs and security leaders to better secure their cloud environments. Danielle is passionate about improving security by building company security culture that starts with employee engagement.

Amazon SageMaker Geospatial Capabilities Now Generally Available with Security Updates and More Use Case Samples

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/amazon-sagemaker-geospatial-capabilities-now-generally-available-with-security-updates-and-more-use-case-samples/

At AWS re:Invent 2022, we previewed Amazon SageMaker geospatial capabilities, allowing data scientists and machine learning (ML) engineers to build, train, and deploy ML models using geospatial data. Geospatial ML with Amazon SageMaker supports access to readily available geospatial data, purpose-built processing operations and open source libraries, pre-trained ML models, and built-in visualization tools with Amazon SageMaker’s geospatial capabilities.

During the preview, we had lots of interest and great feedback from customers. Today, Amazon SageMaker geospatial capabilities are generally available with new security updates and additional sample use cases.
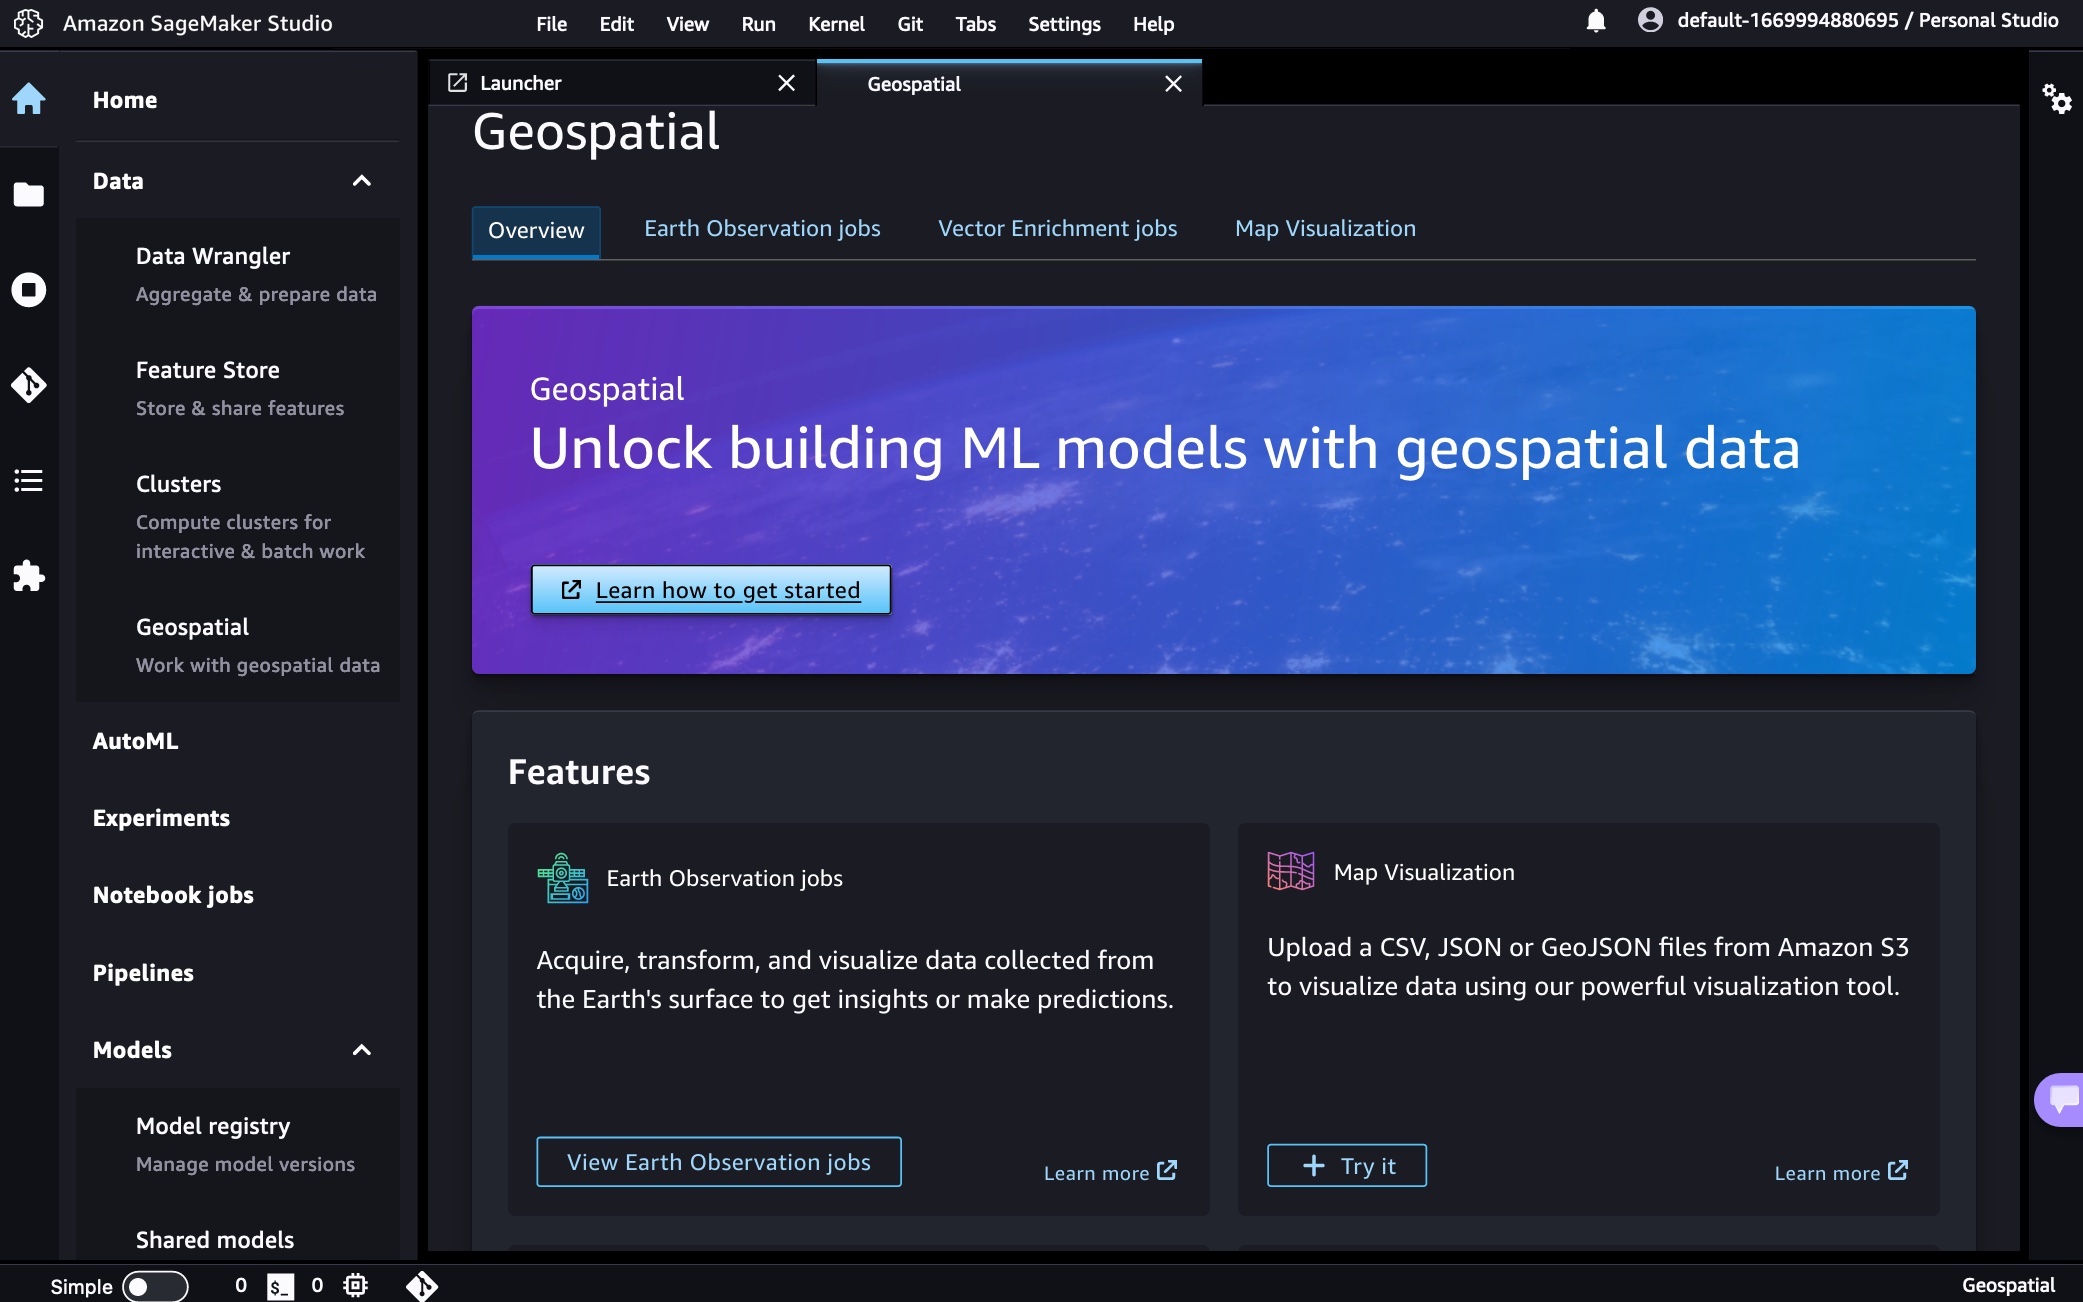
Introducing Geospatial ML features with SageMaker Studio
To get started, use the quick setup to launch Amazon SageMaker Studio in the US West (Oregon) Region. Make sure to use the default Jupyter Lab 3 version when you create a new user in the Studio. Now you can navigate to the homepage in SageMaker Studio. Then select the Data menu and click on Geospatial.

Here is an overview of three key Amazon SageMaker geospatial capabilities:

  • Earth Observation jobs – Acquire, transform, and visualize satellite imagery data using purpose-built geospatial operations or pre-trained ML models to make predictions and get useful insights.
  • Vector Enrichment jobs – Enrich your data with operations, such as converting geographical coordinates to readable addresses.
  • Map Visualization – Visualize satellite images or map data uploaded from a CSV, JSON, or GeoJSON file.

You can create all Earth Observation Jobs (EOJ) in the SageMaker Studio notebook to process satellite data using purpose-built geospatial operations. Here is a list of purpose-built geospatial operations that are supported by the SageMaker Studio notebook:

  • Band Stacking – Combine multiple spectral properties to create a single image.
  • Cloud Masking – Identify cloud and cloud-free pixels to get improved and accurate satellite imagery.
  • Cloud Removal – Remove pixels containing parts of a cloud from satellite imagery.
  • Geomosaic – Combine multiple images for greater fidelity.
  • Land Cover Segmentation – Identify land cover types such as vegetation and water in satellite imagery.
  • Resampling – Scale images to different resolutions.
  • Spectral Index – Obtain a combination of spectral bands that indicate the abundance of features of interest.
  • Temporal Statistics – Calculate statistics through time for multiple GeoTIFFs in the same area.
  • Zonal Statistics – Calculate statistics on user-defined regions.

A Vector Enrichment Job (VEJ) enriches your location data through purpose-built operations for reverse geocoding and map matching. While you need to use a SageMaker Studio notebook to execute a VEJ, you can view all the jobs you create using the user interface. To use the visualization in the notebook, you first need to export your output to your Amazon S3 bucket.

  • Reverse Geocoding – Convert coordinates (latitude and longitude) to human-readable addresses.
  • Map Matching – Snap inaccurate GPS coordinates to road segments.

Using the Map Visualization, you can visualize geospatial data, the inputs to your EOJ or VEJ jobs as well as the outputs exported from your Amazon Simple Storage Service (Amazon S3) bucket.

Security Updates
At GA, we have two major security updates—AWS Key Management Service (AWS KMS) for customer managed AWS KMS key support and Amazon Virtual Private Cloud (Amazon VPC) for geospatial operations in the customer Amazon VPC environment.

AWS KMS customer managed keys offer increased flexibility and control by enabling customers to use their own keys to encrypt geospatial workloads.

You can use KmsKeyId to specify your own key in StartEarthObservationJob and StartVectorEnrichmentJob as an optional parameter. If the customer doesn’t provide KmsKeyId, a service owned key will be used to encrypt the customer content. To learn more, see SageMaker geospatial capabilities AWS KMS Support in the AWS documentation.

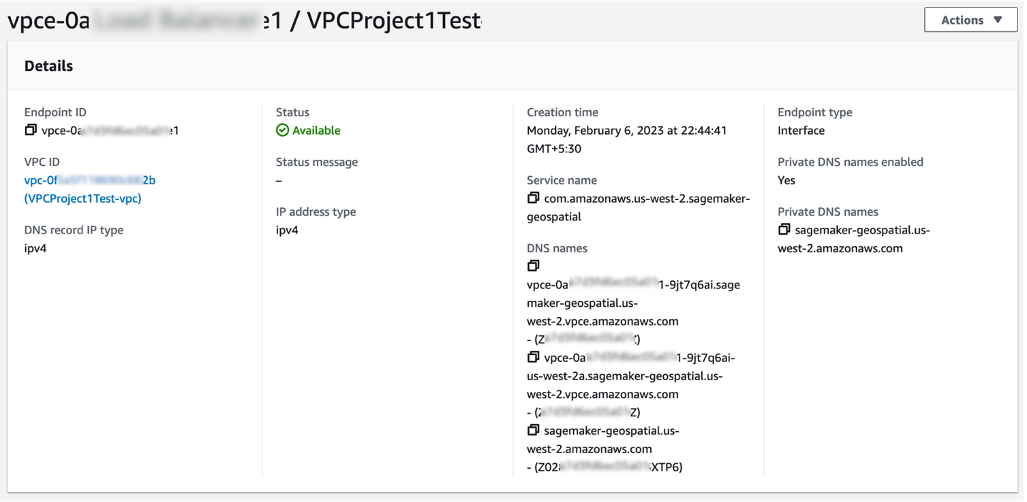
Using Amazon VPC, you have full control over your network environment and can more securely connect to your geospatial workloads on AWS. You can use SageMaker Studio or Notebook in your Amazon VPC environment for SageMaker geospatial operations and execute SageMaker geospatial API operations through an interface VPC endpoint in SageMaker geospatial operations.

To get started with Amazon VPC support, configure Amazon VPC on SageMaker Studio Domain and create a SageMaker geospatial VPC endpoint in your VPC in the Amazon VPC console. Choose the service name as com.amazonaws.us-west-2.sagemaker-geospatial and select the VPC in which to create the VPC endpoint.

All Amazon S3 resources that are used for input or output in EOJ and VEJ operations should have internet access enabled. If you have no direct access to those Amazon S3 resources via the internet, you can grant SageMaker geospatial VPC endpoint ID access to it by changing the corresponding S3 bucket policy. To learn more, see SageMaker geospatial capabilities Amazon VPC Support in the AWS documentation.

Example Use Case for Geospatial ML
Customers across various industries use Amazon SageMaker geospatial capabilities for real-world applications.

Maximize Harvest Yield and Food Security
Digital farming consists of applying digital solutions to help farmers optimize crop production in agriculture through the use of advanced analytics and machine learning. Digital farming applications require working with geospatial data, including satellite imagery of the areas where farmers have their fields located.

You can use SageMaker to identify farm field boundaries in satellite imagery through pre-trained models for land cover classification. Learn about How Xarvio accelerated pipelines of spatial data for digital farming with Amazon SageMaker Geospatial in the AWS Machine Learning Blog. You can find an end-to-end digital farming example notebook via the GitHub repository.

Damage Assessment
As the frequency and severity of natural disasters increase, it’s important that we equip decision-makers and first responders with fast and accurate damage assessment. You can use geospatial imagery to predict natural disaster damage and geospatial data in the immediate aftermath of a natural disaster to rapidly identify damage to buildings, roads, or other critical infrastructure.

From an example notebook, you can train, deploy, and predict natural disaster damage from the floods in Rochester, Australia, in mid-October 2022. We use images from before and after the disaster as input to its trained ML model. The results of the segmentation mask for the Rochester floods are shown in the following images. Here we can see that the model has identified locations within the flooded region as likely damaged.

You can train and deploy a geospatial segmentation model to assess wildfire damages using multi-temporal Sentinel-2 satellite data via GitHub repository. The area of interest for this example is located in Northern California, from a region that was affected by the Dixie Wildfire in 2021.

Monitor Climate Change
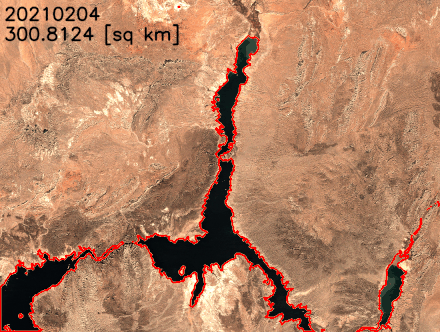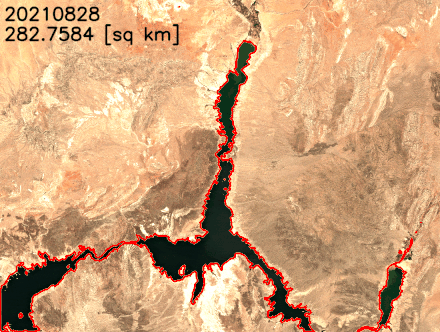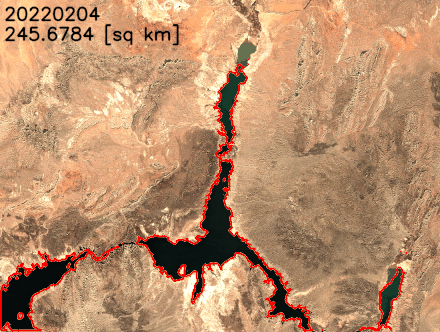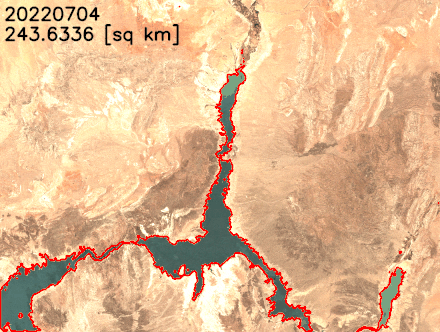
Earth’s climate change increases the risk of drought due to global warming. You can see how to acquire data, perform analysis, and visualize the changes with SageMaker geospatial capabilities to monitor shrinking shoreline caused by climate change in the Lake Mead example, the largest reservoir in the US.

Lake Mead surface area animation

You can find the notebook code for this example in the GitHub repository.

Predict Retail Demand
The new notebook example demonstrates how to use SageMaker geospatial capabilities to perform a vector-based map-matching operation and visualize the results. Map matching allows you to snap noisy GPS coordinates to road segments. With Amazon SageMaker geospatial capabilities, it is possible to perform a VEJ for map matching. This type of job takes a CSV file with route information (such as longitude, latitude, and timestamps of GPS measurements) as input and produces a GeoJSON file that contains the predicted route.

Support Sustainable Urban Development
Arup, one of our customers, uses digital technologies like machine learning to explore the impact of heat on urban areas and the factors that influence local temperatures to deliver better design and support sustainable outcomes. Urban Heat Islands and the associated risks and discomforts are one of the biggest challenges cities are facing today.

Using Amazon SageMaker geospatial capabilities, Arup identifies and measures urban heat factors with earth observation data, which significantly accelerated their ability to counsel clients. It enabled its engineering teams to carry out analytics that weren’t possible previously by providing access to increased volumes, types, and analysis of larger datasets. To learn more, see Facilitating Sustainable City Design Using Amazon SageMaker with Arup in AWS customer stories.

Now Available
Amazon SageMaker geospatial capabilities are now generally available in the US West (Oregon) Region. As part of the AWS Free Tier, you can get started with SageMaker geospatial capabilities for free. The Free Tier lasts 30 days and includes 10 free ml.geospatial.interactive compute hours, up to 10 GB of free storage, and no $150 monthly user fee.

After the 30-day free trial period is complete, or if you exceed the Free Tier limits defined above, you pay for the components outlined on the pricing page.

To learn more, see Amazon SageMaker geospatial capabilities and the Developer Guide. Give it a try and send feedback to AWS re:Post for Amazon SageMaker or through your usual AWS support contacts.

– Channy

Ted Chiang on the Risks of AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/05/ted-chiang-on-the-risks-of-ai.html

Ted Chiang has an excellent essay in the New Yorker: “Will A.I. Become the New McKinsey?”

The question we should be asking is: as A.I. becomes more powerful and flexible, is there any way to keep it from being another version of McKinsey? The question is worth considering across different meanings of the term “A.I.” If you think of A.I. as a broad set of technologies being marketed to companies to help them cut their costs, the question becomes: how do we keep those technologies from working as “capital’s willing executioners”? Alternatively, if you imagine A.I. as a semi-autonomous software program that solves problems that humans ask it to solve, the question is then: how do we prevent that software from assisting corporations in ways that make people’s lives worse? Suppose you’ve built a semi-autonomous A.I. that’s entirely obedient to humans­—one that repeatedly checks to make sure it hasn’t misinterpreted the instructions it has received. This is the dream of many A.I. researchers. Yet such software could easily still cause as much harm as McKinsey has.

Note that you cannot simply say that you will build A.I. that only offers pro-social solutions to the problems you ask it to solve. That’s the equivalent of saying that you can defuse the threat of McKinsey by starting a consulting firm that only offers such solutions. The reality is that Fortune 100 companies will hire McKinsey instead of your pro-social firm, because McKinsey’s solutions will increase shareholder value more than your firm’s solutions will. It will always be possible to build A.I. that pursues shareholder value above all else, and most companies will prefer to use that A.I. instead of one constrained by your principles.

EDITED TO ADD: Ted Chiang’s previous essay, “ChatGPT Is a Blurry JPEG of the Web” is also worth reading.

Building Trustworthy AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/05/building-trustworthy-ai.html

We will all soon get into the habit of using AI tools for help with everyday problems and tasks. We should get in the habit of questioning the motives, incentives, and capabilities behind them, too.

Imagine you’re using an AI chatbot to plan a vacation. Did it suggest a particular resort because it knows your preferences, or because the company is getting a kickback from the hotel chain? Later, when you’re using another AI chatbot to learn about a complex economic issue, is the chatbot reflecting your politics or the politics of the company that trained it?

For AI to truly be our assistant, it needs to be trustworthy. For it to be trustworthy, it must be under our control; it can’t be working behind the scenes for some tech monopoly. This means, at a minimum, the technology needs to be transparent. And we all need to understand how it works, at least a little bit.

Amid the myriad warnings about creepy risks to well-being, threats to democracy, and even existential doom that have accompanied stunning recent developments in artificial intelligence (AI)—and large language models (LLMs) like ChatGPT and GPT-4—one optimistic vision is abundantly clear: this technology is useful. It can help you find information, express your thoughts, correct errors in your writing, and much more. If we can navigate the pitfalls, its assistive benefit to humanity could be epoch-defining. But we’re not there yet.

Let’s pause for a moment and imagine the possibilities of a trusted AI assistant. It could write the first draft of anything: emails, reports, essays, even wedding vows. You would have to give it background information and edit its output, of course, but that draft would be written by a model trained on your personal beliefs, knowledge, and style. It could act as your tutor, answering questions interactively on topics you want to learn about—in the manner that suits you best and taking into account what you already know. It could assist you in planning, organizing, and communicating: again, based on your personal preferences. It could advocate on your behalf with third parties: either other humans or other bots. And it could moderate conversations on social media for you, flagging misinformation, removing hate or trolling, translating for speakers of different languages, and keeping discussions on topic; or even mediate conversations in physical spaces, interacting through speech recognition and synthesis capabilities.

Today’s AIs aren’t up for the task. The problem isn’t the technology—that’s advancing faster than even the experts had guessed—it’s who owns it. Today’s AIs are primarily created and run by large technology companies, for their benefit and profit. Sometimes we are permitted to interact with the chatbots, but they’re never truly ours. That’s a conflict of interest, and one that destroys trust.

The transition from awe and eager utilization to suspicion to disillusionment is a well worn one in the technology sector. Twenty years ago, Google’s search engine rapidly rose to monopolistic dominance because of its transformative information retrieval capability. Over time, the company’s dependence on revenue from search advertising led them to degrade that capability. Today, many observers look forward to the death of the search paradigm entirely. Amazon has walked the same path, from honest marketplace to one riddled with lousy products whose vendors have paid to have the company show them to you. We can do better than this. If each of us are going to have an AI assistant helping us with essential activities daily and even advocating on our behalf, we each need to know that it has our interests in mind. Building trustworthy AI will require systemic change.

First, a trustworthy AI system must be controllable by the user. That means that the model should be able to run on a user’s owned electronic devices (perhaps in a simplified form) or within a cloud service that they control. It should show the user how it responds to them, such as when it makes queries to search the web or external services, when it directs other software to do things like sending an email on a user’s behalf, or modifies the user’s prompts to better express what the company that made it thinks the user wants. It should be able to explain its reasoning to users and cite its sources. These requirements are all well within the technical capabilities of AI systems.

Furthermore, users should be in control of the data used to train and fine-tune the AI system. When modern LLMs are built, they are first trained on massive, generic corpora of textual data typically sourced from across the Internet. Many systems go a step further by fine-tuning on more specific datasets purpose built for a narrow application, such as speaking in the language of a medical doctor, or mimicking the manner and style of their individual user. In the near future, corporate AIs will be routinely fed your data, probably without your awareness or your consent. Any trustworthy AI system should transparently allow users to control what data it uses.

Many of us would welcome an AI-assisted writing application fine tuned with knowledge of which edits we have accepted in the past and which we did not. We would be more skeptical of a chatbot knowledgeable about which of their search results led to purchases and which did not.

You should also be informed of what an AI system can do on your behalf. Can it access other apps on your phone, and the data stored with them? Can it retrieve information from external sources, mixing your inputs with details from other places you may or may not trust? Can it send a message in your name (hopefully based on your input)? Weighing these types of risks and benefits will become an inherent part of our daily lives as AI-assistive tools become integrated with everything we do.

Realistically, we should all be preparing for a world where AI is not trustworthy. Because AI tools can be so incredibly useful, they will increasingly pervade our lives, whether we trust them or not. Being a digital citizen of the next quarter of the twenty-first century will require learning the basic ins and outs of LLMs so that you can assess their risks and limitations for a given use case. This will better prepare you to take advantage of AI tools, rather than be taken advantage by them.

In the world’s first few months of widespread use of models like ChatGPT, we’ve learned a lot about how AI creates risks for users. Everyone has heard by now that LLMs “hallucinate,” meaning that they make up “facts” in their outputs, because their predictive text generation systems are not constrained to fact check their own emanations. Many users learned in March that information they submit as prompts to systems like ChatGPT may not be kept private after a bug revealed users’ chats. Your chat histories are stored in systems that may be insecure.

Researchers have found numerous clever ways to trick chatbots into breaking their safety controls; these work largely because many of the “rules” applied to these systems are soft, like instructions given to a person, rather than hard, like coded limitations on a product’s functions. It’s as if we are trying to keep AI safe by asking it nicely to drive carefully, a hopeful instruction, rather than taking away its keys and placing definite constraints on its abilities.

These risks will grow as companies grant chatbot systems more capabilities. OpenAI is providing developers wide access to build tools on top of GPT: tools that give their AI systems access to your email, to your personal account information on websites, and to computer code. While OpenAI is applying safety protocols to these integrations, it’s not hard to imagine those being relaxed in a drive to make the tools more useful. It seems likewise inevitable that other companies will come along with less bashful strategies for securing AI market share.

Just like with any human, building trust with an AI will be hard won through interaction over time. We will need to test these systems in different contexts, observe their behavior, and build a mental model for how they will respond to our actions. Building trust in that way is only possible if these systems are transparent about their capabilities, what inputs they use and when they will share them, and whose interests they are evolving to represent.

This essay was written with Nathan Sanders, and previously appeared on Gizmodo.com.

How companies are boosting productivity with generative AI

Post Syndicated from Chris Reddington original https://github.blog/2023-05-09-how-companies-are-boosting-productivity-with-generative-ai/

Is your company using generative AI yet?

While it’s still in its infancy, generative AI coding tools are already changing the way developers and companies build software. Generative AI can boost developer and business productivity by automating tasks, improving communication and collaboration, and providing insights that can inform better decision-making.

In this post, we’ll explore the full story of how companies are adopting generative AI to ship software faster, including:

Want to explore the world of generative AI for developers? 🌎

Check out our generative AI guide to learn what it is, how it works, and what it means for developers everywhere.

Get the guide >

What is generative AI?

Generative AI refers to a class of artificial intelligence (AI) systems designed to create new content similar to what humans produce. These systems are trained on large datasets of content that include text, images, audio, music, or code.

Generative AI is an extension of traditional machine learning, which trains models to predict or classify data based on existing patterns. But instead of simply predicting the outcome, generative AI models are designed to identify underlying patterns and structures of the data, and then use that knowledge to quickly generate new content. However, the main difference between the two is one of magnitude and the size of the prediction or generation. Machine learning typically predicts the next word. Generative AI can generate the next paragraph.

AI-generated image from Shutterstack of a developer using a generative AI tool to code faster.

Generative AI tools have attracted particular interest in the business world. From marketing to software development, organizational leaders are increasingly curious about the benefits of the new generative AI applications and products.

“I do think that all companies will adopt generative AI tools in the near future, at least indirectly,” said Albert Ziegler, principal machine learning engineer at GitHub. “The bakery around the corner might have a logo that the designer made using a generative transformer. The neighbor selling knitted socks might have asked Bing where to buy a certain kind of wool. My taxi driver might do their taxes with a certain Excel plugin. This adoption will only increase over time.”

What are some business uses of generative AI tools? 💡

  • Software development: generative AI tools can assist engineers with building, editing, and testing code.
  • Content creation: writers can use generative AI tools to help personalize product descriptions and write ad copy.
  • Design creation: from generating layouts to assisting with graphics, generative AI design tools can help designers create entirely new designs.
  • Video creation: generative AI tools can help videographers with building, editing, or enhancing videos and images.
  • Language translation: translators can use generative AI tools to create communications in different languages.
  • Personalization: generative AI tools can assist businesses with personalizing products and services to meet the needs of individual customers.
  • Operations: from supply chain management to pricing, generative AI tools can help operations professionals drive efficiency.

How generative AI coding tools are changing the developer experience

Generative AI has big implications for developers, as the tools can enable them to code and ship software faster.

How is generative AI affecting software development?⚡

Check out our guide to learn what generative AI coding tools are, what developers are using them for, and how they’re impacting the future of development.

Get the guide >

Similar to how spell check and other automation tools can help writers build content more efficiently, generative AI coding tools can help developers produce cleaner work—and the models powering these tools are getting better by the month. Tools such as GitHub Copilot, for instance, can be used in many parts of the software development lifecycle, including in IDEs, code reviews, and testing.

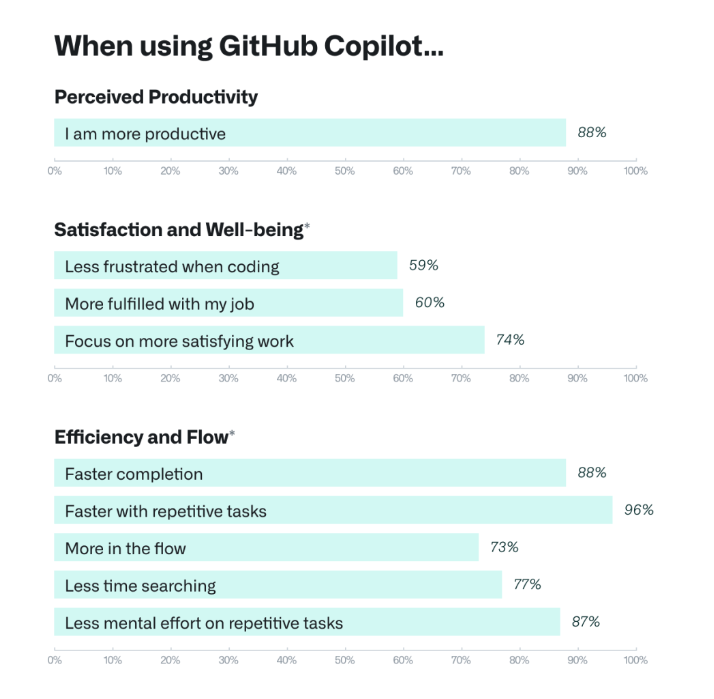
The science backs this up. In 2022, we conducted research into how our generative AI tool, GitHub Copilot, helps developers. Here’s what we found:

Source: Research: quantifying GitHub Copilot’s impact on developer productivity and happiness

GitHub Copilot is only continuing to improve. When the tool was first launched for individuals in June 2022, more than 27% of developers’ code was generated by GitHub Copilot, on average. Today, that number is 46% across all programming languages—and in Java, that jumps to 61%.

How can generative AI tools help you build software? 🚀

These tools can help:

  • Write boilerplate code for various programming languages and frameworks.
  • Find information in documentation to understand what the code does.
  • Identify security vulnerabilities and implement fixes.
  • Streamline code reviews before merging new or edited code.

Explore GitHub’s vision for embedding generative AI into every aspect of the developer workflow.

Using generative AI responsibly 🙏

Like all technologies, responsibility and ethics are important with generative AI.

In February 2023, a group of 10 companies including OpenAI, Adobe, the BBC, and others agreed upon a new set of recommendations on how to use generative AI content in a responsible way.

The recommendations were put together by the Partnership on AI (PAI), an AI research nonprofit, in consultation with more than 50 organizations. The guidelines call for creators and distributors of generative AI to be transparent about what the technology can and can’t do and disclose when users might be interacting with this type of content (by using watermarks, disclaimers, or traceable elements in an AI model’s training data).

Is generative AI accurate? 🔑

Businesses should be aware that while generative AI tools can speed up the creation of content, they should not be solely relied upon as a source of truth. A recent study suggests that people can identify whether AI-generated content is real or fake only 50% of the time. Here at GitHub, we named our generative AI tool “GitHub Copilot” to signify just this—the tool can help, but at the end of the day, it’s just a copilot. The developer needs to take responsibility for ensuring that the finished code is accurate and complete.

How companies are using generative AI

Even as generative AI models and tools continue to rapidly advance, businesses are already exploring how to incorporate these into their day-to-day operations.

This is particularly true for software development teams.

“Going forward, tech companies that don’t adopt generative AI tools will have a significant productivity disadvantage,” Ziegler said. “Given how much faster this technology can help developers build, organizations that don’t adopt these tools or create their own will have a harder time in the marketplace.”

3 primary generative AI business models for organizations 📈

Enterprises all over the world are using generative AI tools to transform how work gets done. Three of the business models organizations use include:

  • Model as a Service (MaaS): Companies access generative AI models through the cloud and use them to create new content. OpenAI employs this model, which licenses its GPT-3 AI model, the platform behind ChatGPT. This option offers low-risk, low-cost access to generative AI, with limited upfront investment and high flexibility.
  • Built-in apps: Companies build new—or existing—apps on top of generative AI models to create new experiences. GitHub Copilot uses this model, which relies on Codex to analyze the context of the code to provide intelligent suggestions on how to complete it. This option offers high customization and specialized solutions with scalability.
  • Vertical integration: Vertical integration leverages existing systems to enhance the offerings. For instance, companies may use generative AI models to analyze large amounts of data and make predictions about prices or improve the accuracy of their services.

Duolingo, one of the largest language-learning apps in the world, is one company that recently adopted generative AI capabilities. They chose GitHub’s generative AI tool, GitHub Copilot, to help their developers write and ship code faster, while improving test coverage. Duolingo’s CTO Severin Hacker said GitHub Copilot delivered immediate benefits to the team, enabling them to code quickly and deliver their best work.

”[The tool] stops you from getting distracted when you’re doing deep work that requires a lot of your brain power,” Hacker noted. “You spend less time on routine work and more time on the hard stuff. With GitHub Copilot, our developers stay in the flow state and keep momentum instead of clawing through code libraries or documentation.”

After adopting GitHub Copilot and the GitHub platform, Duolingo saw a:

  • 25% increase in developer speed for those who are new to working with a specific repository
  • 10% increase in developer speed for those who are familiar with the respective codebase
  • 67% decrease in median code review turnaround time

“I don’t know of anything available today that’s remotely close to what we can get with GitHub Copilot,” Hacker said.

Looking forward

Generative AI is changing the world of software development. And it’s just getting started. The technology is quickly improving and more use cases are being identified across the software development lifecycle. With the announcement of GitHub Copilot X, our vision for the future of AI-powered software development, we’re committed to installing AI capabilities into every step of the developer workflow. There’s no better time to get started with generative AI at your company.

AI Hacking Village at DEF CON This Year

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/05/ai-hacking-village-at-def-con-this-year.html

At DEF CON this year, Anthropic, Google, Hugging Face, Microsoft, NVIDIA, OpenAI and Stability AI will all open up their models for attack.

The DEF CON event will rely on an evaluation platform developed by Scale AI, a California company that produces training for AI applications. Participants will be given laptops to use to attack the models. Any bugs discovered will be disclosed using industry-standard responsible disclosure practices.

Web Summit Rio 2023: Building an app in 18 minutes with GitHub Copilot X

Post Syndicated from Thomas Dohmke original https://github.blog/2023-05-05-web-summit-rio-2023-building-an-app-in-18-minutes-with-github-copilot-x/

Missed GitHub CEO Thomas Dohmke’s Web Summit Rio 2023 talk? Read his remarks and get caught up on everything GitHub Copilot X.

Hello, Rio! I’m Thomas, and I’m a developer. I’ve been looking forward to this for some time, about a year. When I first planned this talk, I wanted to talk about the future of artificial intelligence and applications. But then I thought, why not show you the full power live on stage. Build something with code.

I’ve been a developer my entire adult life. I’ve been coding since 1989. But as CEO, I haven’t been able to light up my contribution graph in a while. Like all of you, like every developer, my energy, my creativity every day is finite. And all the distractions of life—from the personal to the professional—from morning to night, gradually zaps my creative energy.

When I wake up, I’m at my most creative and sometimes I have a big, light bulb idea. But as soon as the coffee is poured, the distractions start. Slack messages and emails flood in. I have to review a document before a customer presentation. And then I hear my kids yell as their football flew over the fence. And, of course, they want me to go over to our neighbors’ and get it.

Then…I sit back down, I am in wall-to-wall meetings. And by the time the sun comes down, that idea I had in the morning—it’s gone! It’s midnight and I can’t even keep my eyes open. To be honest, in all this, I usually don’t even want to get started because the perception of having to do all the mundane tasks, all the boilerplate work that comes with coding, stops me in my tracks. And I know this is true for so many developers.

The point is: boilerplate sucks! All busywork in life, but especially repetitive work is a barrier between us and what we want to achieve. Every day, building endless boilerplate prevents developers from creating a new idea that will change the world. But with AI, these barriers are about to be shattered.

You’ve likely seen the memes about the 10x developer. It’s a common internet joke—people have claimed the 10x developer many times. With GitHub Copilot and now Copilot X, it’s time for us to redefine this! It isn’t that developers need to strive to be 10x, it’s that every developer deserves to be made 10 times more productive. With AI at every step, we will truly create without captivity. With AI at every step, we will realize the 10x developer.

Imagine: 10 days of work, done in one day. 10 hours of work, done in one hour. 10 minutes of work, done with a single prompt command. This will allow us to amplify our truest self-expression. It will help a new generation of developers learn and build as fast as their minds. And because of this, we’ll emerge into a new spring of digital creativity, where every light bulb idea we have when we open our eyes for the day can be fully realized no matter what life throws at us.

During my presentation, I built a snake game in 15 minutes.

This morning I woke up, and I wanted to build something. I wanted to build my own snake game, originally created back in 1976. It’s a classic. So, 15 minutes are left on my timer. And I’m going to build this snake game. Let’s bring up Copilot X and get going!

See how you can 10x your developer superpowers. Discover GitHub Copilot X.

Large Language Models and Elections

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/05/large-language-models-and-elections.html

Earlier this week, the Republican National Committee released a video that it claims was “built entirely with AI imagery.” The content of the ad isn’t especially novel—a dystopian vision of America under a second term with President Joe Biden—but the deliberate emphasis on the technology used to create it stands out: It’s a “Daisy” moment for the 2020s.

We should expect more of this kind of thing. The applications of AI to political advertising have not escaped campaigners, who are already “pressure testing” possible uses for the technology. In the 2024 presidential election campaign, you can bank on the appearance of AI-generated personalized fundraising emails, text messages from chatbots urging you to vote, and maybe even some deepfaked campaign avatars. Future candidates could use chatbots trained on data representing their views and personalities to approximate the act of directly connecting with people. Think of it like a whistle-stop tour with an appearance in every living room. Previous technological revolutions—railroad, radio, television, and the World Wide Web—transformed how candidates connect to their constituents, and we should expect the same from generative AI. This isn’t science fiction: The era of AI chatbots standing in as avatars for real, individual people has already begun, as the journalist Casey Newton made clear in a 2016 feature about a woman who used thousands of text messages to create a chatbot replica of her best friend after he died.

The key is interaction. A candidate could use tools enabled by large language models, or LLMs—the technology behind apps such as ChatGPT and the art-making DALL-E—to do micro-polling or message testing, and to solicit perspectives and testimonies from their political audience individually and at scale. The candidates could potentially reach any voter who possesses a smartphone or computer, not just the ones with the disposable income and free time to attend a campaign rally. At its best, AI could be a tool to increase the accessibility of political engagement and ease polarization. At its worst, it could propagate misinformation and increase the risk of voter manipulation. Whatever the case, we know political operatives are using these tools. To reckon with their potential now isn’t buying into the hype—it’s preparing for whatever may come next.

On the positive end, and most profoundly, LLMs could help people think through, refine, or discover their own political ideologies. Research has shown that many voters come to their policy positions reflexively, out of a sense of partisan affiliation. The very act of reflecting on these views through discourse can change, and even depolarize, those views. It can be hard to have reflective policy conversations with an informed, even-keeled human discussion partner when we all live within a highly charged political environment; this is a role almost custom-designed for LLM. In US politics, it is a truism that the most valuable resource in a campaign is time. People are busy and distracted. Campaigns have a limited window to convince and activate voters. Money allows a candidate to purchase time: TV commercials, labor from staffers, and fundraising events to raise even more money. LLMs could provide campaigns with what is essentially a printing press for time.

If you were a political operative, which would you rather do: play a short video on a voter’s TV while they are folding laundry in the next room, or exchange essay-length thoughts with a voter on your candidate’s key issues? A staffer knocking on doors might need to canvass 50 homes over two hours to find one voter willing to have a conversation. OpenAI charges pennies to process about 800 words with its latest GPT-4 model, and that cost could fall dramatically as competitive AIs become available. People seem to enjoy interacting with chatbots; Open’s product reportedly has the fastest-growing user base in the history of consumer apps.

Optimistically, one possible result might be that we’ll get less annoyed with the deluge of political ads if their messaging is more usefully tailored to our interests by AI tools. Though the evidence for microtargeting’s effectiveness is mixed at best, some studies show that targeting the right issues to the right people can persuade voters. Expecting more sophisticated, AI-assisted approaches to be more consistently effective is reasonable. And anything that can prevent us from seeing the same 30-second campaign spot 20 times a day seems like a win.

AI can also help humans effectuate their political interests. In the 2016 US presidential election, primitive chatbots had a role in donor engagement and voter-registration drives: simple messaging tasks such as helping users pre-fill a voter-registration form or reminding them where their polling place is. If it works, the current generation of much more capable chatbots could supercharge small-dollar solicitations and get-out-the-vote campaigns.

And the interactive capability of chatbots could help voters better understand their choices. An AI chatbot could answer questions from the perspective of a candidate about the details of their policy positions most salient to an individual user, or respond to questions about how a candidate’s stance on a national issue translates to a user’s locale. Political organizations could similarly use them to explain complex policy issues, such as those relating to the climate or health care or…anything, really.

Of course, this could also go badly. In the time-honored tradition of demagogues worldwide, the LLM could inconsistently represent the candidate’s views to appeal to the individual proclivities of each voter.

In fact, the fundamentally obsequious nature of the current generation of large language models results in them acting like demagogues. Current LLMs are known to hallucinate—or go entirely off-script—and produce answers that have no basis in reality. These models do not experience emotion in any way, but some research suggests they have a sophisticated ability to assess the emotion and tone of their human users. Although they weren’t trained for this purpose, ChatGPT and its successor, GPT-4, may already be pretty good at assessing some of their users’ traits—say, the likelihood that the author of a text prompt is depressed. Combined with their persuasive capabilities, that means that they could learn to skillfully manipulate the emotions of their human users.

This is not entirely theoretical. A growing body of evidence demonstrates that interacting with AI has a persuasive effect on human users. A study published in February prompted participants to co-write a statement about the benefits of social-media platforms for society with an AI chatbot configured to have varying views on the subject. When researchers surveyed participants after the co-writing experience, those who interacted with a chatbot that expressed that social media is good or bad were far more likely to express the same view than a control group that didn’t interact with an “opinionated language model.”

For the time being, most Americans say they are resistant to trusting AI in sensitive matters such as health care. The same is probably true of politics. If a neighbor volunteering with a campaign persuades you to vote a particular way on a local ballot initiative, you might feel good about that interaction. If a chatbot does the same thing, would you feel the same way? To help voters chart their own course in a world of persuasive AI, we should demand transparency from our candidates. Campaigns should have to clearly disclose when a text agent interacting with a potential voter—through traditional robotexting or the use of the latest AI chatbots—is human or automated.

Though companies such as Meta (Facebook’s parent company) and Alphabet (Google’s) publish libraries of traditional, static political advertising, they do so poorly. These systems would need to be improved and expanded to accommodate user-level differentiation in ad copy to offer serviceable protection against misuse.

A public, anonymized log of chatbot conversations could help hold candidates’ AI representatives accountable for shifting statements and digital pandering. Candidates who use chatbots to engage voters may not want to make all transcripts of those conversations public, but their users could easily choose to share them. So far, there is no shortage of people eager to share their chat transcripts, and in fact, an online database exists of nearly 200,000 of them. In the recent past, Mozilla has galvanized users to opt into sharing their web data to study online misinformation.

We also need stronger nationwide protections on data privacy, as well as the ability to opt out of targeted advertising, to protect us from the potential excesses of this kind of marketing. No one should be forcibly subjected to political advertising, LLM-generated or not, on the basis of their Internet searches regarding private matters such as medical issues. In February, the European Parliament voted to limit political-ad targeting to only basic information, such as language and general location, within two months of an election. This stands in stark contrast to the US, which has for years failed to enact federal data-privacy regulations. Though the 2018 revelation of the Cambridge Analytica scandal led to billions of dollars in fines and settlements against Facebook, it has so far resulted in no substantial legislative action.

Transparency requirements like these are a first step toward oversight of future AI-assisted campaigns. Although we should aspire to more robust legal controls on campaign uses of AI, it seems implausible that these will be adopted in advance of the fast-approaching 2024 general presidential election.

Credit the RNC, at least, with disclosing that their recent ad was AI-generated—a transparent attempt at publicity still counts as transparency. But what will we do if the next viral AI-generated ad tries to pass as something more conventional?

As we are all being exposed to these rapidly evolving technologies for the first time and trying to understand their potential uses and effects, let’s push for the kind of basic transparency protection that will allow us to know what we’re dealing with.

This essay was written with Nathan Sanders, and previously appeared on the Atlantic.

EDITED TO ADD (5/12): Better article on the “daisy” ad.

DevSecOps with Amazon CodeGuru Reviewer CLI and Bitbucket Pipelines

Post Syndicated from Bineesh Ravindran original https://aws.amazon.com/blogs/devops/devsecops-with-amazon-codeguru-reviewer-cli-and-bitbucket-pipelines/

DevSecOps refers to a set of best practices that integrate security controls into the continuous integration and delivery (CI/CD) workflow. One of the first controls is Static Application Security Testing (SAST). SAST tools run on every code change and search for potential security vulnerabilities before the code is executed for the first time. Catching security issues early in the development process significantly reduces the cost of fixing them and the risk of exposure.

This blog post, shows how we can set up a CI/CD using Bitbucket Pipelines and Amazon CodeGuru Reviewer . Bitbucket Pipelines is a cloud-based continuous delivery system that allows developers to automate builds, tests, and security checks with just a few lines of code. CodeGuru Reviewer is a cloud-based static analysis tool that uses machine learning and automated reasoning to generate code quality and security recommendations for Java and Python code.

We demonstrate step-by-step how to set up a pipeline with Bitbucket Pipelines, and how to call CodeGuru Reviewer from there. We then show how to view the recommendations produced by CodeGuru Reviewer in Bitbucket Code Insights, and how to triage and manage recommendations during the development process.

Bitbucket Overview

Bitbucket is a Git-based code hosting and collaboration tool built for teams. Bitbucket’s best-in-class Jira and Trello integrations are designed to bring the entire software team together to execute a project. Bitbucket provides one place for a team to collaborate on code from concept to cloud, build quality code through automated testing, and deploy code with confidence. Bitbucket makes it easy for teams to collaborate and reduce issues found during integration by providing a way to combine easily and test code frequently. Bitbucket gives teams easy access to tools needed in other parts of the feedback loop, from creating an issue to deploying on your hardware of choice. It also provides more advanced features for those customers that need them, like SAML authentication and secrets storage.

Solution Overview

Bitbucket Pipelines uses a Docker container to perform the build steps. You can specify any Docker image accessible by Bitbucket, including private images, if you specify credentials to access them. The container starts and then runs the build steps in the order specified in your configuration file. The build steps specified in the configuration file are nothing more than shell commands executed on the Docker image. Therefore, you can run scripts, in any language supported by the Docker image you choose, as part of the build steps. These scripts can be stored either directly in your repository or an Internet-accessible location. This solution demonstrates an easy way to integrate Bitbucket pipelines with AWS CodeReviewer using bitbucket-pipelines.yml file.

You can interact with your Amazon Web Services (AWS)  account from your Bitbucket Pipeline using the  OpenID Connect (OIDC)  feature. OpenID Connect is an identity layer above the OAuth 2.0 protocol.

Now that you understand how Bitbucket and your AWS Account securely communicate with each other, let’s look into the overall summary of steps to configure this solution.

  1. Fork the repository
  2. Configure Bitbucket Pipelines as an IdP on AWS.
  3. Create an IAM role.
  4. Add repository variables needed for pipeline
  5. Adding the CodeGuru Reviewer CLI to your pipeline
  6. Review CodeGuru recommendations

Now let’s look into each step in detail. To configure the solution, follow  steps mentioned below.

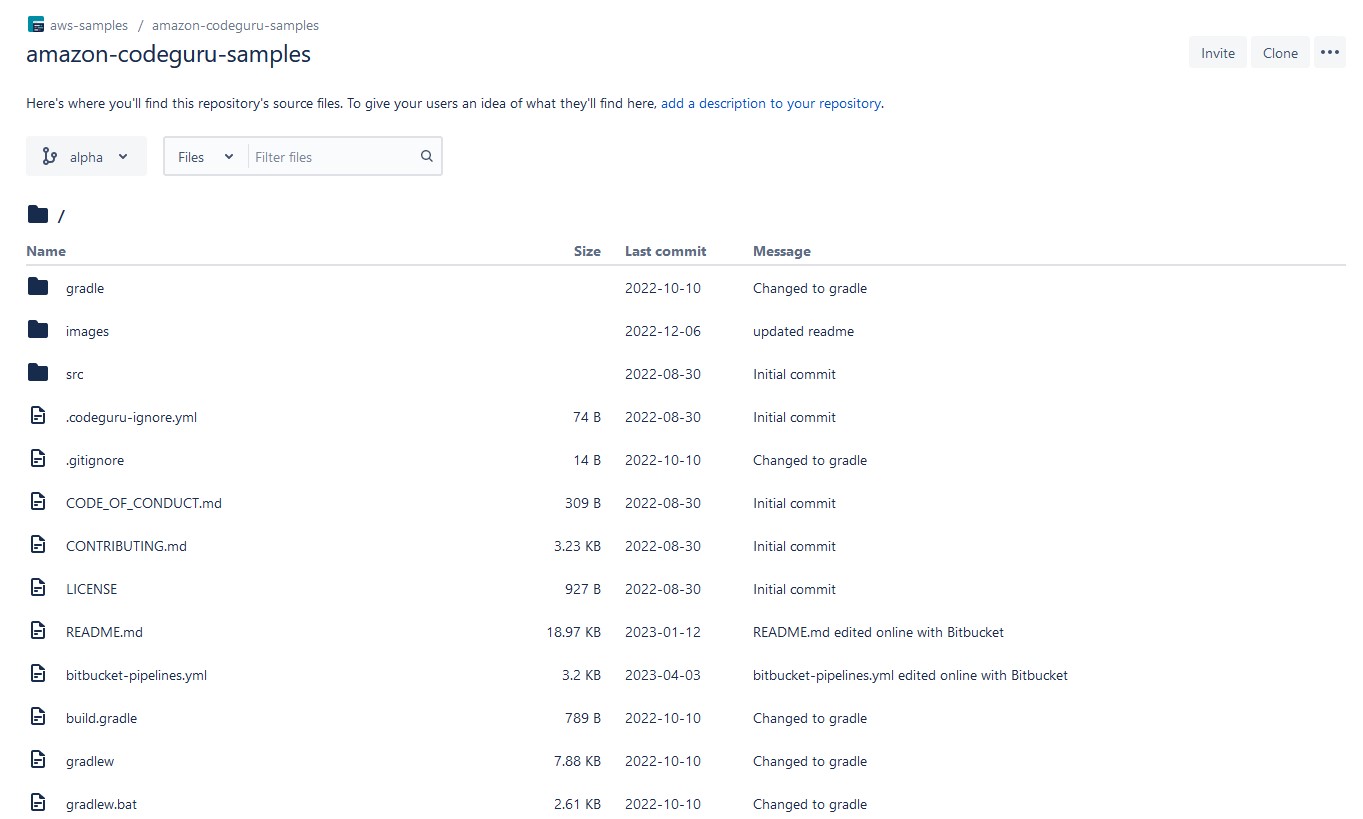
Step 1: Fork this repo

Log in to Bitbucket and choose **Fork** to fork this example app to your Bitbucket account.

https://bitbucket.org/aws-samples/amazon-codeguru-samples

Fork amazon-codeguru-samples bitbucket repository.

Figure 1 : Fork amazon-codeguru-samples bitbucket repository.

Step 2: Configure Bitbucket Pipelines as an Identity Provider on AWS

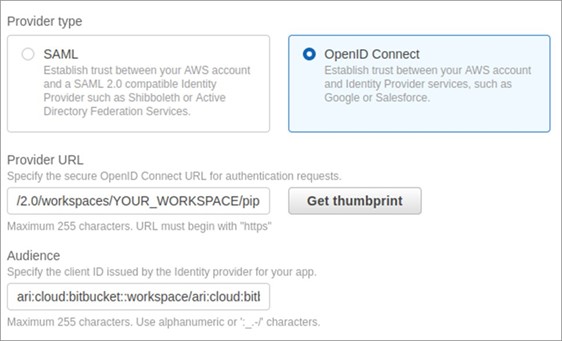
Configuring Bitbucket Pipelines as an IdP in IAM enables Bitbucket Pipelines to issue authentication tokens to users to connect to AWS.
In your Bitbucket repo, go to Repository Settings > OpenID Connect. Note the provider URL and the Audience variable on that screen.

The Identity Provider URL will look like this:

https://api.bitbucket.org/2.0/workspaces/YOUR_WORKSPACE/pipelines-config/identity/oidc  – This is the issuer URL for authentication requests. This URL issues a  token to a requester automatically as part of the workflow. See more detail about issuer URL in RFC . Here “YOUR_WORKSPACE” need to be replaced with name of your bitbucket workspace.

And the Audience will look like:

ari:cloud:bitbucket::workspace/ari:cloud:bitbucket::workspace/84c08677-e352-4a1c-a107-6df387cfeef7  – This is the recipient the token is intended for. See more detail about audience in Request For Comments (RFC) which is memorandum published by the Internet Engineering Task Force(IETF) describing methods and behavior for  securely transmitting information between two parties usinf JSON Web Token ( JWT).

Configure Bitbucket Pipelines as an Identity Provider on AWS

Figure 2 : Configure Bitbucket Pipelines as an Identity Provider on AWS

Next, navigate to the IAM dashboard > Identity Providers > Add provider, and paste in the above info. This tells AWS that Bitbucket Pipelines is a token issuer.

Step 3: Create a custom policy

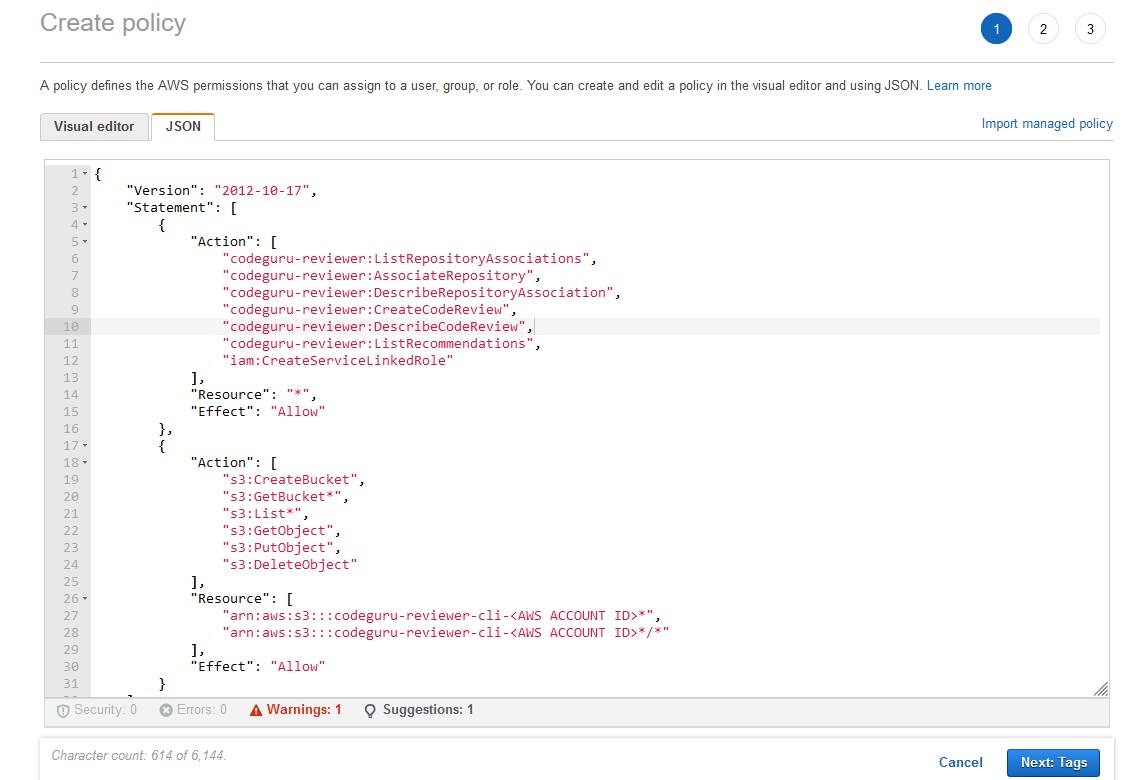
You can always use the CLI with Admin credentials but if you want to have a specific role to use the CLI, your credentials must have at least the following permissions:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Action": [
                "codeguru-reviewer:ListRepositoryAssociations",
                "codeguru-reviewer:AssociateRepository",
                "codeguru-reviewer:DescribeRepositoryAssociation",
                "codeguru-reviewer:CreateCodeReview",
                "codeguru-reviewer:DescribeCodeReview",
                "codeguru-reviewer:ListRecommendations",
                "iam:CreateServiceLinkedRole"
            ],
            "Resource": "*",
            "Effect": "Allow"
        },
        {
            "Action": [
                "s3:CreateBucket",
                "s3:GetBucket*",
                "s3:List*",
                "s3:GetObject",
                "s3:PutObject",
                "s3:DeleteObject"
            ],
            "Resource": [
                "arn:aws:s3:::codeguru-reviewer-cli-<AWS ACCOUNT ID>*",
                "arn:aws:s3:::codeguru-reviewer-cli-<AWS ACCOUNT ID>*/*"
            ],
            "Effect": "Allow"
        }
    ]
}

To create an IAM policy, navigate to the IAM dashboard > Policies > Create Policy

Now then paste the above mentioned json document into the json tab as shown in screenshot below and replace <AWS ACCOUNT ID>   with your own AWS Account ID

Create a Policy.

Figure 3 : Create a Policy.

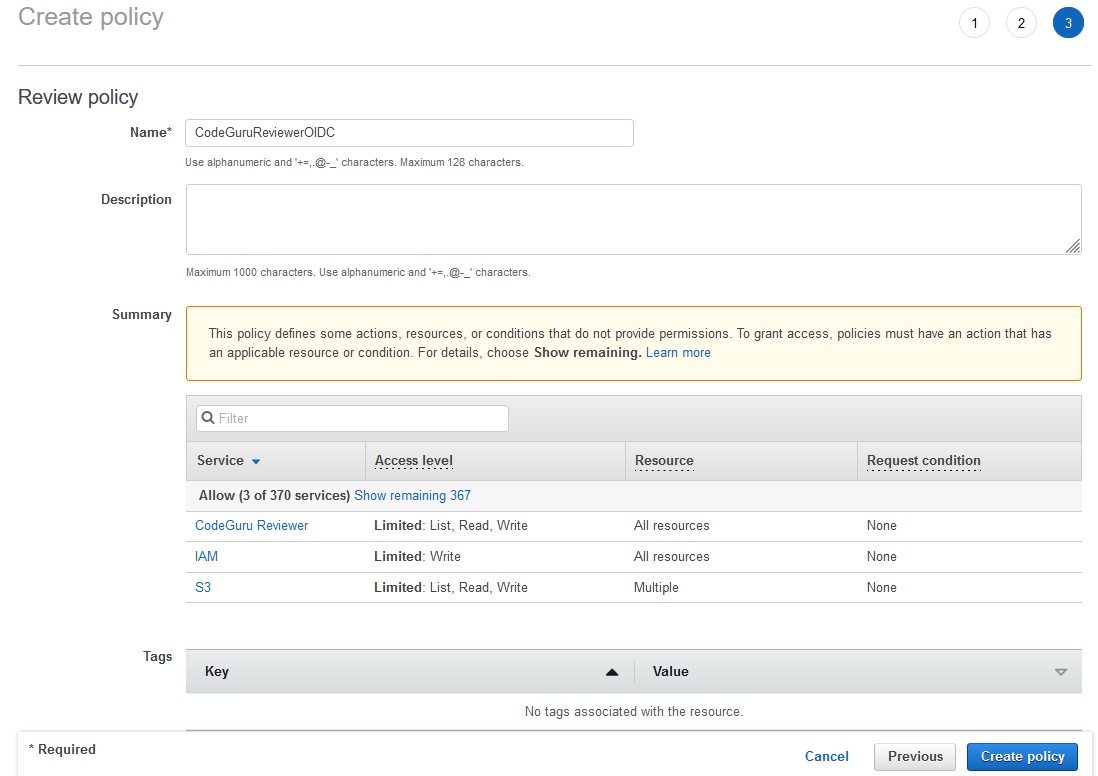
Name your policy; in our example, we name it CodeGuruReviewerOIDC.

Review and Create a IAM policy.

Figure 4 : Review and Create a IAM policy.

Step 4: Create an IAM Role

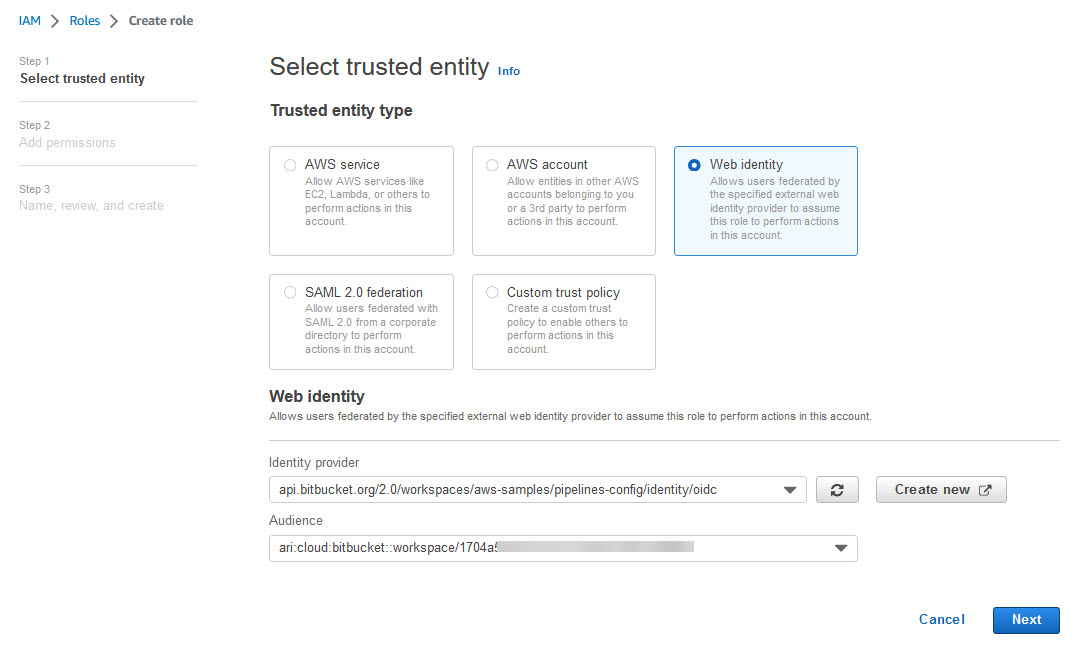
Once you’ve enabled Bitbucket Pipelines as a token issuer, you need to configure permissions for those tokens so they can execute actions on AWS.
To create an IAM web identity role, navigate to the IAM dashboard > Roles > Create Role, and choose the IdP and audience you just created.

Create an IAM role

Figure 5 : Create an IAM role

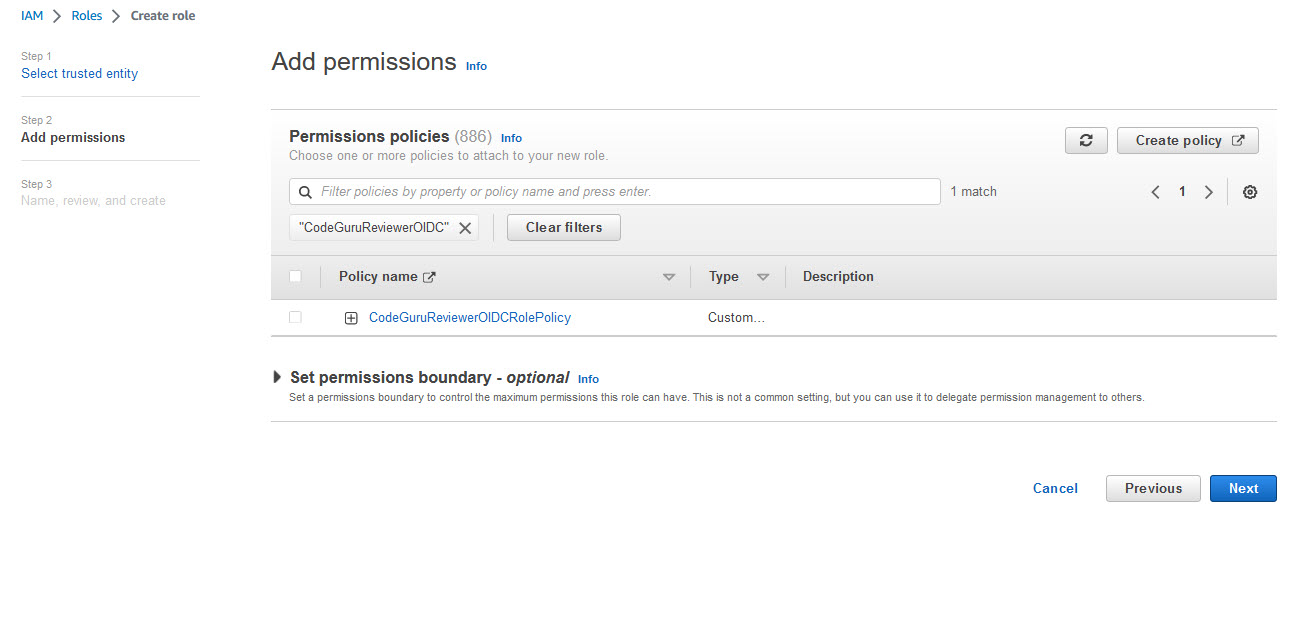
Next, select the “CodeGuruReviewerOIDC “ policy to attach to the role.

Assign policy to role

Figure 6 : Assign policy to role

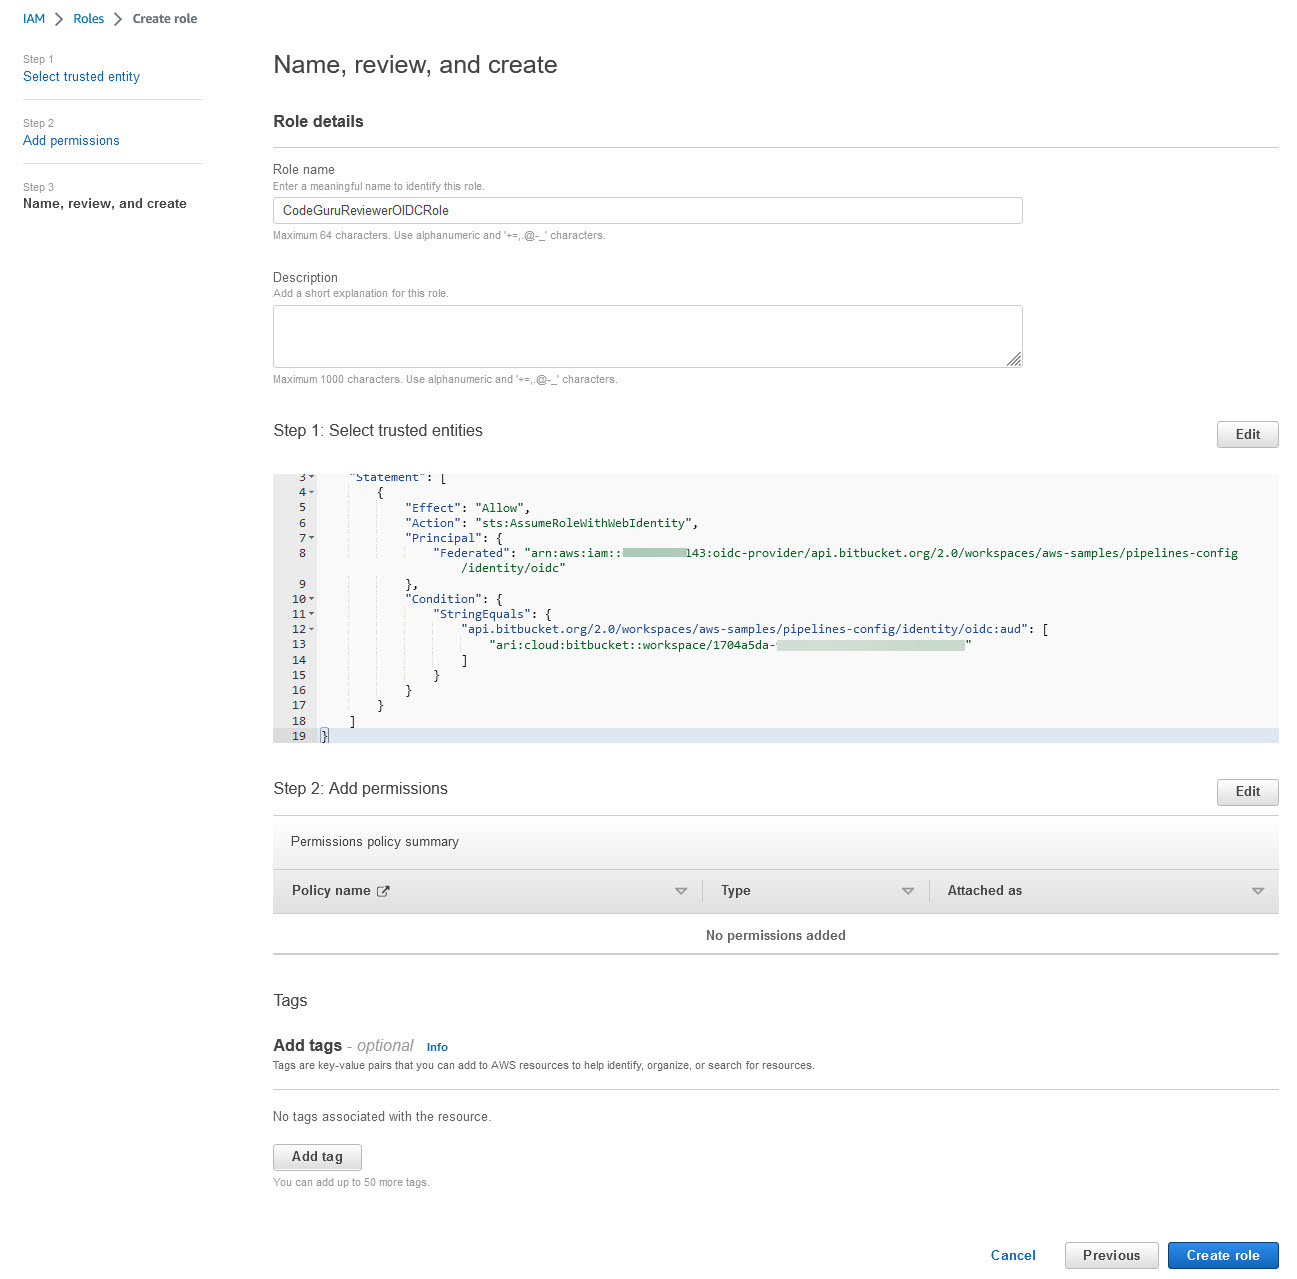
 Review and Create role

Figure 7 : Review and Create role

Name your role; in our example, we name it CodeGuruReviewerOIDCRole.

After adding a role, copy the Amazon Resource Name (ARN) of the role created:

The Amazon Resource Name (ARN) will look like this:

arn:aws:iam::000000000000:role/CodeGuruReviewerOIDCRole

we will need this in a later step when we create AWS_OIDC_ROLE_ARN as a repository variable.

Step 5: Add repository variables needed for pipeline

Variables are configured as environment variables in the build container. You can access the variables from the bitbucket-pipelines.yml file or any script that you invoke by referring to them. Pipelines provides a set of default variables that are available for builds, and can be used in scripts .Along with default variables we need to configure few additional variables called Repository Variables which are used to pass special parameter to the pipeline.

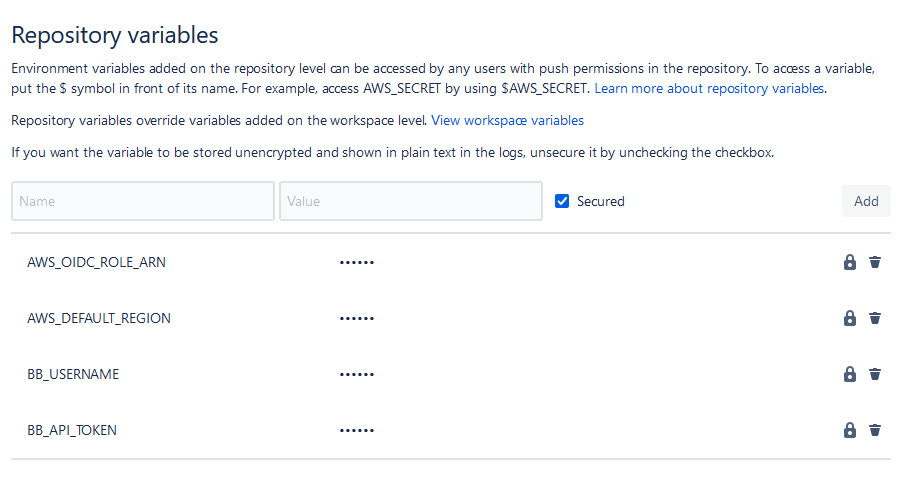
Create repository variables

Figure 8 : Create repository variables

Figure 8 Create repository variables

Below mentioned are the few repository variables that need to be configured for this solution.

1.AWS_DEFAULT_REGION       Create a repository variableAWS_DEFAULT_REGION with value “us-east-1”

2.BB_API_TOKEN          Create a new repository variable BB_API_TOKEN and paste the below created App password as the value

App passwords are user-based access tokens for scripting tasks and integrating tools (such as CI/CD tools) with Bitbucket Cloud.These access tokens have reduced user access (specified at the time of creation) and can be useful for scripting, CI/CD tools, and testing Bitbucket connected applications while they are in development.
To create an App password:

    • Select your avatar (Your profile and settings) from the navigation bar at the top of the screen.
    • Under Settings, select Personal settings.
    • On the sidebar, select App passwords.
    • Select Create app password.
    • Give the App password a name, usually related to the application that will use the password.
    • Select the permissions the App password needs. For detailed descriptions of each permission, see: App password permissions.
    • Select the Create button. The page will display the New app password dialog.
    • Copy the generated password and either record or paste it into the application you want to give access. The password is only displayed once and can’t be retrieved later.

3.BB_USERNAME  Create a repository variable BB_USERNAME and add your bitbucket username as the value of this variable

4.AWS_OIDC_ROLE_ARN

After adding a role in Step 4, copy the Amazon Resource Name (ARN) of the role created:

The Amazon Resource Name (ARN) will look something like this:

    arn:aws:iam::000000000000:role/CodeGuruReviewerOIDCRole

and create AWS_OIDC_ROLE_ARN as a repository variable in the target Bitbucket repository.

Step 6: Adding the CodeGuru Reviewer CLI to your pipeline

In order to add CodeGuruRevewer CLi to your pipeline update the bitbucket-pipelines.yml file as shown below

#  Template maven-build

 #  This template allows you to test and build your Java project with Maven.
 #  The workflow allows running tests, code checkstyle and security scans on the default branch.

 # Prerequisites: pom.xml and appropriate project structure should exist in the repository.

 image: docker-public.packages.atlassian.com/atlassian/bitbucket-pipelines-mvn-python3-awscli

 pipelines:
  default:
    - step:
        name: Build Source Code
        caches:
          - maven
        script:
          - cd $BITBUCKET_CLONE_DIR
          - chmod 777 ./gradlew
          - ./gradlew build
        artifacts:
          - build/**
    - step: 
        name: Download and Install CodeReviewer CLI   
        script:
          - curl -OL https://github.com/aws/aws-codeguru-cli/releases/download/0.2.3/aws-codeguru-cli.zip
          - unzip aws-codeguru-cli.zip
        artifacts:
          - aws-codeguru-cli/**
    - step:
        name: Run CodeGuruReviewer 
        oidc: true
        script:
          - export AWS_DEFAULT_REGION=$AWS_DEFAULT_REGION
          - export AWS_ROLE_ARN=$AWS_OIDC_ROLE_ARN
          - export S3_BUCKET=$S3_BUCKET

          # Setup aws cli
          - export AWS_WEB_IDENTITY_TOKEN_FILE=$(pwd)/web-identity-token
          - echo $BITBUCKET_STEP_OIDC_TOKEN > $(pwd)/web-identity-token
          - aws configure set web_identity_token_file "${AWS_WEB_IDENTITY_TOKEN_FILE}"
          - aws configure set role_arn "${AWS_ROLE_ARN}"
          - aws sts get-caller-identity

          # setup codegurureviewercli
          - export PATH=$PATH:./aws-codeguru-cli/bin
          - chmod 777 ./aws-codeguru-cli/bin/aws-codeguru-cli

          - export SRC=$BITBUCKET_CLONE_DIR/src
          - export OUTPUT=$BITBUCKET_CLONE_DIR/test-reports
          - export CODE_INSIGHTS=$BITBUCKET_CLONE_DIR/bb-report

          # Calling Code Reviewer CLI
          - ./aws-codeguru-cli/bin/aws-codeguru-cli --region $AWS_DEFAULT_REGION  --root-dir $BITBUCKET_CLONE_DIR --build $BITBUCKET_CLONE_DIR/build/classes/java --src $SRC --output $OUTPUT --no-prompt --bitbucket-code-insights $CODE_INSIGHTS        
        artifacts:
          - test-reports/*.* 
          - target/**
          - bb-report/**
    - step: 
        name: Upload Code Insights Artifacts to Bitbucket Reports 
        script:
          - chmod 777 upload.sh
          - ./upload.sh bb-report/report.json bb-report/annotations.json
    - step:
        name: Upload Artifacts to Bitbucket Downloads       # Optional Step
        script:
          - pipe: atlassian/bitbucket-upload-file:0.3.3
            variables:
              BITBUCKET_USERNAME: $BB_USERNAME
              BITBUCKET_APP_PASSWORD: $BB_API_TOKEN
              FILENAME: '**/*.json'
    - step:
          name: Validate Findings     #Optional Step
          script:
            # Looking into CodeReviewer results and failing if there are Critical recommendations
            - grep -o "Critical" test-reports/recommendations.json | wc -l
            - count="$(grep -o "Critical" test-reports/recommendations.json | wc -l)"
            - echo $count
            - if (( $count > 0 )); then
            - echo "Critical findings discovered. Failing."
            - exit 1
            - fi
          artifacts:
            - '**/*.json'

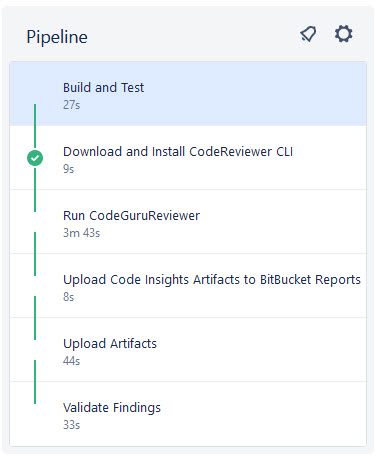
Let’s look into the pipeline file to understand various steps defined in this pipeline

Bitbucket pipeline execution steps

Figure 9 : Bitbucket pipeline execution steps

Step 1) Build Source Code

In this step source code is downloaded into a working directory and build using Gradle.All the build artifacts are then passed on to next step

Step 2) Download and Install Amazon CodeGuru Reviewer CLI
In this step Amazon CodeGuru Reviewer is CLI is downloaded from a public github repo and extracted into working directory. All artifacts downloaded and extracted are then passed on to next step

Step 3) Run CodeGuruReviewer

This step uses flag oidc: true which declares you are using  the OIDC authentication method, while AWS_OIDC_ROLE_ARN declares the role created in the previous step that contains all of the necessary permissions to deal with AWS resources.
Further repository variables are exported, which is then used to set AWS CLI .Amazon CodeGuruReviewer CLI which was downloaded and extracted in previous step is then used to invoke CodeGuruReviewer along with some parameters .

Following are the parameters that are passed on to the CodeGuruReviewer CLI
--region $AWS_DEFAULT_REGION   The AWS region in which CodeGuru Reviewer will run (in this blog we used us-east-1).

--root-dir $BITBUCKET_CLONE_DIR The root directory of the repository that CodeGuru Reviewer should analyze.

--build $BITBUCKET_CLONE_DIR/build/classes/java Points to the build artifacts. Passing the Java build artifacts allows CodeGuru Reviewer to perform more in-depth bytecode analysis, but passing the build artifacts is not required.

--src $SRC Points the source code that should be analyzed. This can be used to focus the analysis on certain source files, e.g., to exclude test files. This parameter is optional, but focusing on relevant code can shorten analysis time and cost.

--output $OUTPUT The directory where CodeGuru Reviewer will store its recommendations.

--no-prompt This ensures that CodeGuru Reviewer does run in interactive mode where it pauses for user input.

–-bitbucket-code-insights $CODE_INSIGHTS The location where recommendations in Bitbucket CodeInsights format should be written to.

Once Amazon CodeGuruReviewer scans the code based on the above parameters, it generates two json files (reports.json and annotations.json) Code Insight Reports which is then passed on as artifacts to the next step.

Step 4) Upload Code Insights Artifacts to Bitbucket Reports
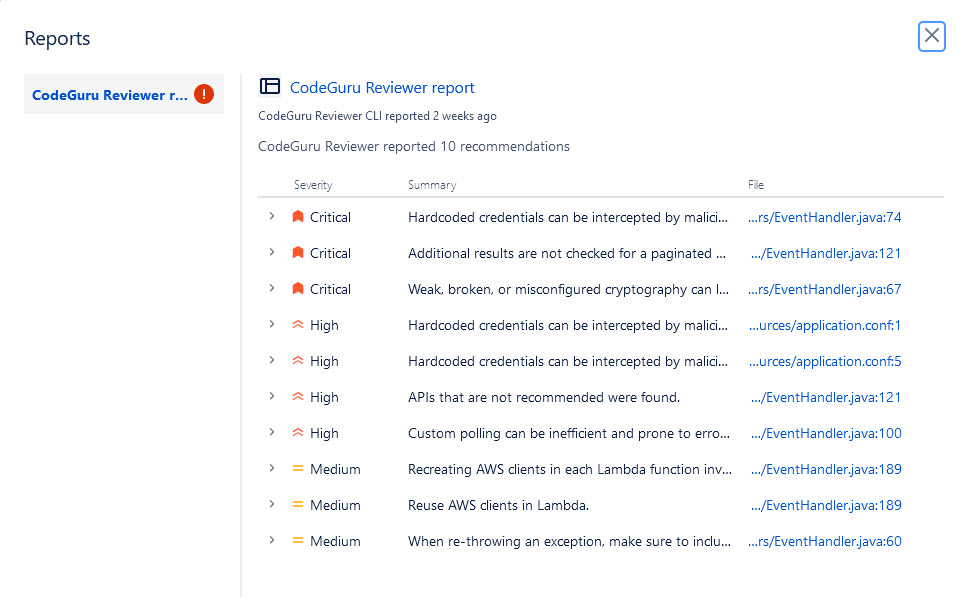
In this step code Insight Report generated by Amazon CodeGuru Reviewer is then uploaded to Bitbucket Reports. This makes the report available in the reports section in the pipeline as displayed in the screenshot

CodeGuru Reviewer Report

Figure 10 : CodeGuru Reviewer Report

Step 5) [Optional] Upload the copy of these reports to Bitbucket Downloads
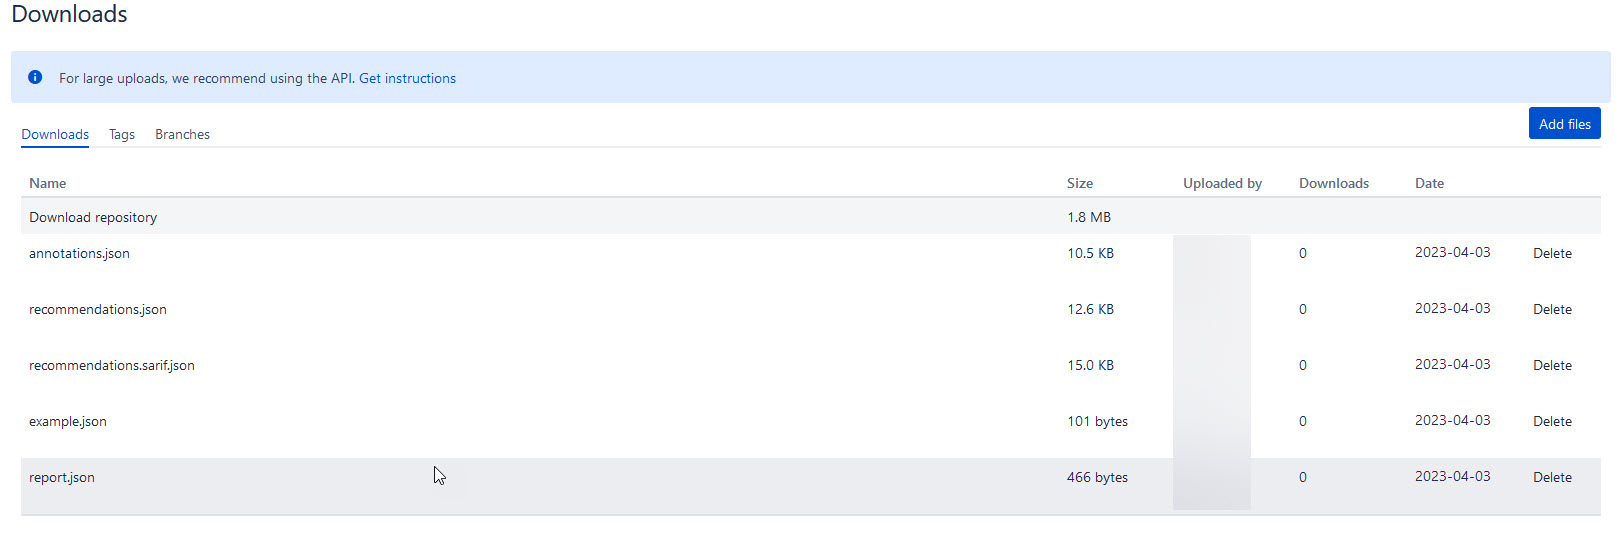
This is an Optional step where you can upload the artifacts to Bitbucket Downloads. This is especially useful because the artifacts inside a build pipeline gets deleted after 14 days of the pipeline run. Using Bitbucket Downloads, you can store these artifacts for a much longer duration.

Bitbucket downloads

Figure 11 : Bitbucket downloads

Step 6) [Optional] Validate Findings by looking into results and failing is there are any Critical Recommendations
This is an optional step showcasing how the results for CodeGururReviewer can be used to trigger the success and failure of a Bitbucket pipeline. In this step the pipeline fails, if a critical recommendation exists in report.

Step 7: Review CodeGuru recommendations

CodeGuru Reviewer supports different recommendation formats, including CodeGuru recommendation summaries, SARIF, and Bitbucket CodeInsights.

Keeping your Pipeline Green

Now that CodeGuru Reviewer is running in our pipeline, we need to learn how to unblock ourselves if there are recommendations. The easiest way to unblock a pipeline after is to address the CodeGuru recommendation. If we want to validate on our local machine that a change addresses a recommendation using the same CLI that we use as part of our pipeline.
Sometimes, it is not convenient to address a recommendation. E.g., because there are mitigations outside of the code that make the recommendation less relevant, or simply because the team agrees that they don’t want to block deployments on recommendations unless they are critical. For these cases, developers can add a .codeguru-ignore.yml file to their repository where they can use a variety of criteria under which a recommendation should not be reported. Below we explain all available criteria to filter recommendations. Developers can use any subset of those criteria in their .codeguru-ignore.yml file. We will give a specific example in the following sections.

version: 1.0 # The version number is mandatory. All other entries are optional.

# The CodeGuru Reviewer CLI produces a recommendations.json file which contains deterministic IDs for each
# recommendation. This ID can be excluded so that this recommendation will not be reported in future runs of the
# CLI.
 ExcludeById:
 - '4d2c43618a2dac129818bef77093730e84a4e139eef3f0166334657503ecd88d'
# We can tell the CLI to exclude all recommendations below a certain severity. This can be useful in CI/CD integration.
 ExcludeBelowSeverity: 'HIGH'
# We can exclude all recommendations that have a certain tag. Available Tags can be found here:
# https://docs.aws.amazon.com/codeguru/detector-library/java/tags/
# https://docs.aws.amazon.com/codeguru/detector-library/python/tags/
 ExcludeTags:
  - 'maintainability'
# We can also exclude recommendations by Detector ID. Detector IDs can be found here:
# https://docs.aws.amazon.com/codeguru/detector-library
 ExcludeRecommendations:
# Ignore all recommendations for a given Detector ID 
  - detectorId: 'java/[email protected]'
# Ignore all recommendations for a given Detector ID in a provided set of locations.
# Locations can be written as Unix GLOB expressions using wildcard symbols.
  - detectorId: 'java/[email protected]'
    Locations:
      - 'src/main/java/com/folder01/*.java'
# Excludes all recommendations in the provided files. Files can be provided as Unix GLOB expressions.
 ExcludeFiles:
  - tst/**

The recommendations will still be reported in the CodeGuru Reviewer console, but not by the CodeGuru Reviewer CLI and thus they will not block the pipeline anymore.

Conclusion

In this post, we outlined how you can set up a CI/CD pipeline using Bitbucket Pipelines, and Amazon CodeGuru Reviewer and  we outlined how you can integrate Amazon CodeGuru Reviewer CLI with the Bitbucket cloud-based continuous delivery system that allows developers to automate builds, tests, and security checks with just a few lines of code. We showed you how to create a Bitbucket pipeline job and integrate the CodeGuru Reviewer CLI to detect issues in your Java and Python code, and access the recommendations for remediating these issues.

We presented an example where you can stop the build upon finding critical violations. Furthermore, we discussed how you could upload these artifacts to BitBucket downloads and store these artifacts for a much longer duration. The CodeGuru Reviewer CLI offers you a one-line command to scan any code on your machine and retrieve recommendations .You can use the CLI to integrate CodeGuru Reviewer into your favorite CI tool, as a pre-commit hook,   in your workflow. In turn, you can combine CodeGuru Reviewer with Dynamic Application Security Testing (DAST) and Software Composition Analysis (SCA) tools to achieve a hybrid application security testing method that helps you combine the inside-out and outside-in testing approaches, cross-reference results, and detect vulnerabilities that both exist and are exploitable.

If you need hands-on keyboard support, then AWS Professional Services can help implement this solution in your enterprise, and introduce you to our AWS DevOps services and offerings.

About the authors:

Bineesh Ravindran

Bineesh Ravindran

Bineesh is Solutions Architect at Amazon Webservices (AWS) who is passionate about technology and love to help customers solve problems. Bineesh has over 20 years of experience in designing and implementing enterprise applications. He works with AWS partners and customers to provide them with architectural guidance for building scalable architecture and execute strategies to drive adoption of AWS services. When he’s not working, he enjoys biking, aquascaping and playing badminton..

Martin Schaef

Martin Schaef

Martin Schaef is an Applied Scientist in the AWS CodeGuru team since 2017. Prior to that, he worked at SRI International in Menlo Park, CA, and at the United Nations University in Macau. He received his PhD from University of Freiburg in 2011.

Optimizing data with automated intelligent document processing solutions

Post Syndicated from Deependra Shekhawat original https://aws.amazon.com/blogs/architecture/optimizing-data-with-automated-intelligent-document-processing-solutions/

Many organizations struggle to effectively manage and derive insights from the large amount of unstructured data locked in emails, PDFs, images, scanned documents, and more. The variety of formats, document layouts, and text makes it difficult for any standard Optical Character Recognition (OCR) to extract key insights from these data sources.

To help organizations overcome these document management and information extraction challenges, AWS offers connected, pre-trained artificial intelligence (AI) service APIs that help drive business outcomes from these document-based rich data sources.

This blog post describes a cost-effective, scalable automated intelligent document processing solution that leverages a Natural Processing Language (NLP) engine using Amazon Textract and Amazon Comprehend. This solution helps customers take advantage of industry leading machine learning (ML) technology in their document workflows without the need for in-house ML expertise.

Customer document management challenges

Customers across industry verticals experience the following document management challenges:

  • Extraction process accuracy varies significantly when applied to diverse sources; specifically handwritten text, images, and scanned documents.
  • Existing scripting and rule-based solutions cannot provide customer domain or problem-specific classifiers.
  • Traditional document management systems cannot consider feedback from domain experts to improve the learning process.
  • The Personally Identifiable Information (PII) data-handling is not robust or customizable, causing data privacy leakage concern.
  • Many manual interventions are required to complete the entire process.

Automated intelligent document processing solution

We introduced an automated intelligent document processing implementation to address key document management challenges. At the heart of the solution is a NLP engine that combines:

The full solution also leverages other AWS services as described in the following diagram (Figure 1) and steps to develop and operate a cost-effective and scalable architecture for document processing. It effectively extracts text from document types including PDFs, images, scanned documents, Microsoft Excel workbooks, and more.

AI-based intelligent document processing engine

Figure 1: AI-based intelligent document processing engine

Solution overview

Let’s explore the automated intelligent document processing solution step by step.

  1. The document upload engine or business users upload the respective files or documents through a custom web application to the designated Amazon Simple Storage Service (Amazon S3) bucket.
  2. The event-based architecture signals an Amazon S3 push event to invoke the respective AWS Lambda function to start document pre-processing.
  3. The Lambda function evaluates the document payload, leverages Amazon Simple Queue Service (Amazon SQS) for async processing, prepares document metadata, stores it in Amazon DynamoDB, and calls the NLP engine to perform the information extraction process.
  4. The NLP engine leverages Amazon Textract for text extraction from a variety of sources and leverages document metadata to optimize the appropriate API calls (for example, form, tabular, or PDF).
    • Amazon Textract output is fed into Amazon Comprehend which consumes the extracted text and performs entity parsing, line/paragraph-based sentiment analysis, and document/paragraph classification. For better accuracy, we leverage a custom classifier within Amazon Comprehend.
    • Amazon Comprehend also provides key APIs to mask PII data before it is used for any further consumption. The solution offers the ability to configure masking rules for each PII entity per masking requirements.
    • To ensure the solution has capability to handle data from Microsoft Excel workbooks, we developed a custom parser using Python running inside an AWS Lambda function. Depending on the document metadata, this function can be invoked.
  5. Output of Amazon Comprehend is then fed to ML models deployed using Amazon SageMaker depending on additional use cases configured by the customer to complement the overall process with ML-based recommendations, predictions, and personalization.
  6. Once the NLP engine completes its processing, the job completion notification event signals another AWS Lambda function and updates the status in the respective Amazon SQS queue.
  7. The Lambda post-processing function parses the resultant content generated by the NLP engine and stores it in the Amazon DynamoDB and Amazon S3 bucket. This step is responsible for the required data augmentation, key entities validation, and default value assignment to create a data structure that could be consumed by the presentation/visualization layer.
  8. Users get the flexibility to see the extracted information and compare it with the original document extract in the custom user interface (UI). They can provide their feedback on extraction and entity parsing accuracy. From a user access management perspective, Amazon Cognito provides authorization and authentication.

Customer benefits

The automated intelligent document processing solution helps customers:

  • Increase overall document management efficiency by 50-60%, leveraging automation and nullifying manual interventions
  • Reduce in-house team involvement in administrative activities by up to 70% using integrated and connected processing workflows
  • Gain better visibility into key contractual obligations with features such as Document Classification (helps properly route documents to the respective process/team) and Obligation Extraction
  • Utilize a UI-based feedback mechanism for in-house domain experts/reviewers to see and validate the extracted information and offer feedback to inform further model training

From a cost-optimization perspective, depending on document type and required information, only the respective Amazon Textract APIs calls are submitted. (For example, it is not worth using form/table-based Textract API calls for a Know Your Customer (KYC) document such as a driver’s license or passport when the AnalyzeID API is the most efficient solution.)

To maximize solution benefits, customers should invest time in building well-defined taxonomies ahead of using the document processing solution to accommodate their own use cases or industry domain-specific requirements. Their taxonomy input highlights only relevant keys and takes respective actions in case the requires keys are not extracted.

Vertical industry use cases

As mentioned, this document processing solution can be used across industry segments. Let’s explore some practical use cases. For example, it can help insurance industry professionals to accelerate claim processing and customer KYC-related processes. By extracting the key entities from the claim documents, mapping them against the customer defined taxonomy, and integrating with Amazon SageMaker models for anomaly detection (anomalous claims), insurance providers can improve claim management and customer satisfaction.

In the healthcare industry, the solution can help with medical records and report processing, key medical entity extraction, and customer data masking.

The document processing solution can help the banking industry by automating check processing and delivering the ability to extract key entities like payer, payee, date, and amount from the checks.

Conclusion

Manual document processing is resource-intensive, time consuming, and costly. Customers need to allocate resources to process large volume documents, lowering business agility. Their employees are performing manual “stare and compare” tasks, potentially reducing worker morale and preventing them from focusing where their efforts are better placed.

Intelligent document processing helps businesses overcome these challenges by automating the classification, extraction, and analysis of data. This expedites decision cycles, allocates resources to high-value tasks, and reduces costs.

Pre-trained APIs of AWS AI services allow for quick classification, extraction, and data analyzation from scores of documents. This solution also has industry specific features that can quickly process specialized industry specific documents. This blog discussed the foundational architecture to helps to accelerate implementation of any specific document processing use case.

Security Risks of AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/04/security-risks-of-ai.html

Stanford and Georgetown have a new report on the security risks of AI—particularly adversarial machine learning—based on a workshop they held on the topic.

Jim Dempsey, one of the workshop organizers, wrote a blog post on the report:

As a first step, our report recommends the inclusion of AI security concerns within the cybersecurity programs of developers and users. The understanding of how to secure AI systems, we concluded, lags far behind their widespread adoption. Many AI products are deployed without institutions fully understanding the security risks they pose. Organizations building or deploying AI models should incorporate AI concerns into their cybersecurity functions using a risk management framework that addresses security throughout the AI system life cycle. It will be necessary to grapple with the ways in which AI vulnerabilities are different from traditional cybersecurity bugs, but the starting point is to assume that AI security is a subset of cybersecurity and to begin applying vulnerability management practices to AI-based features. (Andy Grotto and I have vigorously argued against siloing AI security in its own governance and policy vertical.)

Our report also recommends more collaboration between cybersecurity practitioners, machine learning engineers, and adversarial machine learning researchers. Assessing AI vulnerabilities requires technical expertise that is distinct from the skill set of cybersecurity practitioners, and organizations should be cautioned against repurposing existing security teams without additional training and resources. We also note that AI security researchers and practitioners should consult with those addressing AI bias. AI fairness researchers have extensively studied how poor data, design choices, and risk decisions can produce biased outcomes. Since AI vulnerabilities may be more analogous to algorithmic bias than they are to traditional software vulnerabilities, it is important to cultivate greater engagement between the two communities.

Another major recommendation calls for establishing some form of information sharing among AI developers and users. Right now, even if vulnerabilities are identified or malicious attacks are observed, this information is rarely transmitted to others, whether peer organizations, other companies in the supply chain, end users, or government or civil society observers. Bureaucratic, policy, and cultural barriers currently inhibit such sharing. This means that a compromise will likely remain mostly unnoticed until long after attackers have successfully exploited vulnerabilities. To avoid this outcome, we recommend that organizations developing AI models monitor for potential attacks on AI systems, create—formally or informally—a trusted forum for incident information sharing on a protected basis, and improve transparency.

AI to Aid Democracy

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/04/ai-to-aid-democracy.html

There’s good reason to fear that AI systems like ChatGPT and GPT4 will harm democracy. Public debate may be overwhelmed by industrial quantities of autogenerated argument. People might fall down political rabbit holes, taken in by superficially convincing bullshit, or obsessed by folies à deux relationships with machine personalities that don’t really exist.

These risks may be the fallout of a world where businesses deploy poorly tested AI systems in a battle for market share, each hoping to establish a monopoly.

But dystopia isn’t the only possible future. AI could advance the public good, not private profit, and bolster democracy instead of undermining it. That would require an AI not under the control of a large tech monopoly, but rather developed by government and available to all citizens. This public option is within reach if we want it.

An AI built for public benefit could be tailor-made for those use cases where technology can best help democracy. It could plausibly educate citizens, help them deliberate together, summarize what they think, and find possible common ground. Politicians might use large language models, or LLMs, like GPT4 to better understand what their citizens want.

Today, state-of-the-art AI systems are controlled by multibillion-dollar tech companies: Google, Meta, and OpenAI in connection with Microsoft. These companies get to decide how we engage with their AIs and what sort of access we have. They can steer and shape those AIs to conform to their corporate interests. That isn’t the world we want. Instead, we want AI options that are both public goods and directed toward public good.

We know that existing LLMs are trained on material gathered from the internet, which can reflect racist bias and hate. Companies attempt to filter these data sets, fine-tune LLMs, and tweak their outputs to remove bias and toxicity. But leaked emails and conversations suggest that they are rushing half-baked products to market in a race to establish their own monopoly.

These companies make decisions with huge consequences for democracy, but little democratic oversight. We don’t hear about political trade-offs they are making. Do LLM-powered chatbots and search engines favor some viewpoints over others? Do they skirt controversial topics completely? Currently, we have to trust companies to tell us the truth about the trade-offs they face.

A public option LLM would provide a vital independent source of information and a testing ground for technological choices with big democratic consequences. This could work much like public option health care plans, which increase access to health services while also providing more transparency into operations in the sector and putting productive pressure on the pricing and features of private products. It would also allow us to figure out the limits of LLMs and direct their applications with those in mind.

We know that LLMs often “hallucinate,” inferring facts that aren’t real. It isn’t clear whether this is an unavoidable flaw of how they work, or whether it can be corrected for. Democracy could be undermined if citizens trust technologies that just make stuff up at random, and the companies trying to sell these technologies can’t be trusted to admit their flaws.

But a public option AI could do more than check technology companies’ honesty. It could test new applications that could support democracy rather than undermining it.

Most obviously, LLMs could help us formulate and express our perspectives and policy positions, making political arguments more cogent and informed, whether in social media, letters to the editor, or comments to rule-making agencies in response to policy proposals. By this we don’t mean that AI will replace humans in the political debate, only that they can help us express ourselves. If you’ve ever used a Hallmark greeting card or signed a petition, you’ve already demonstrated that you’re OK with accepting help to articulate your personal sentiments or political beliefs. AI will make it easier to generate first drafts, and provide editing help and suggest alternative phrasings. How these AI uses are perceived will change over time, and there is still much room for improvement in LLMs—but their assistive power is real. People are already testing and speculating on their potential for speechwriting, lobbying, and campaign messaging. Highly influential people often rely on professional speechwriters and staff to help develop their thoughts, and AI could serve a similar role for everyday citizens.

If the hallucination problem can be solved, LLMs could also become explainers and educators. Imagine citizens being able to query an LLM that has expert-level knowledge of a policy issue, or that has command of the positions of a particular candidate or party. Instead of having to parse bland and evasive statements calibrated for a mass audience, individual citizens could gain real political understanding through question-and-answer sessions with LLMs that could be unfailingly available and endlessly patient in ways that no human could ever be.

Finally, and most ambitiously, AI could help facilitate radical democracy at scale. As Carnegie Mellon professor of statistics Cosma Shalizi has observed, we delegate decisions to elected politicians in part because we don’t have time to deliberate on every issue. But AI could manage massive political conversations in chat rooms, on social networking sites, and elsewhere: identifying common positions and summarizing them, surfacing unusual arguments that seem compelling to those who have heard them, and keeping attacks and insults to a minimum.

AI chatbots could run national electronic town hall meetings and automatically summarize the perspectives of diverse participants. This type of AI-moderated civic debate could also be a dynamic alternative to opinion polling. Politicians turn to opinion surveys to capture snapshots of popular opinion because they can only hear directly from a small number of voters, but want to understand where voters agree or disagree.

Looking further into the future, these technologies could help groups reach consensus and make decisions. Early experiments by the AI company DeepMind suggest that LLMs can build bridges between people who disagree, helping bring them to consensus. Science fiction writer Ruthanna Emrys, in her remarkable novel A Half-Built Garden, imagines how AI might help people have better conversations and make better decisions—rather than taking advantage of these biases to maximize profits.

This future requires an AI public option. Building one, through a government-directed model development and deployment program, would require a lot of effort—and the greatest challenges in developing public AI systems would be political.

Some technological tools are already publicly available. In fairness, tech giants like Google and Meta have made many of their latest and greatest AI tools freely available for years, in cooperation with the academic community. Although OpenAI has not made the source code and trained features of its latest models public, competitors such as Hugging Face have done so for similar systems.

While state-of-the-art LLMs achieve spectacular results, they do so using techniques that are mostly well known and widely used throughout the industry. OpenAI has only revealed limited details of how it trained its latest model, but its major advance over its earlier ChatGPT model is no secret: a multi-modal training process that accepts both image and textual inputs.

Financially, the largest-scale LLMs being trained today cost hundreds of millions of dollars. That’s beyond ordinary people’s reach, but it’s a pittance compared to U.S. federal military spending—and a great bargain for the potential return. While we may not want to expand the scope of existing agencies to accommodate this task, we have our choice of government labs, like the National Institute of Standards and Technology, the Lawrence Livermore National Laboratory, and other Department of Energy labs, as well as universities and nonprofits, with the AI expertise and capability to oversee this effort.

Instead of releasing half-finished AI systems for the public to test, we need to make sure that they are robust before they’re released—and that they strengthen democracy rather than undermine it. The key advance that made recent AI chatbot models dramatically more useful was feedback from real people. Companies employ teams to interact with early versions of their software to teach them which outputs are useful and which are not. These paid users train the models to align to corporate interests, with applications like web search (integrating commercial advertisements) and business productivity assistive software in mind.

To build assistive AI for democracy, we would need to capture human feedback for specific democratic use cases, such as moderating a polarized policy discussion, explaining the nuance of a legal proposal, or articulating one’s perspective within a larger debate. This gives us a path to “align” LLMs with our democratic values: by having models generate answers to questions, make mistakes, and learn from the responses of human users, without having these mistakes damage users and the public arena.

Capturing that kind of user interaction and feedback within a political environment suspicious of both AI and technology generally will be challenging. It’s easy to imagine the same politicians who rail against the untrustworthiness of companies like Meta getting far more riled up by the idea of government having a role in technology development.

As Karl Popper, the great theorist of the open society, argued, we shouldn’t try to solve complex problems with grand hubristic plans. Instead, we should apply AI through piecemeal democratic engineering, carefully determining what works and what does not. The best way forward is to start small, applying these technologies to local decisions with more constrained stakeholder groups and smaller impacts.

The next generation of AI experimentation should happen in the laboratories of democracy: states and municipalities. Online town halls to discuss local participatory budgeting proposals could be an easy first step. Commercially available and open-source LLMs could bootstrap this process and build momentum toward federal investment in a public AI option.

Even with these approaches, building and fielding a democratic AI option will be messy and hard. But the alternative—shrugging our shoulders as a fight for commercial AI domination undermines democratic politics—will be much messier and much worse.

This essay was written with Henry Farrell and Nathan Sanders, and previously appeared on Slate.com.

EDITED TO ADD: Linux Weekly News discussion.

Automate discovery of data relationships using ML and Amazon Neptune graph technology

Post Syndicated from Moira Lennox original https://aws.amazon.com/blogs/big-data/automate-discovery-of-data-relationships-using-ml-and-amazon-neptune-graph-technology/

Data mesh is a new approach to data management. Companies across industries are using a data mesh to decentralize data management to improve data agility and get value from data. However, when a data producer shares data products on a data mesh self-serve web portal, it’s neither intuitive nor easy for a data consumer to know which data products they can join to create new insights. This is especially true in a large enterprise with thousands of data products.

This post shows how to use machine learning (ML) and Amazon Neptune to create automated recommendations to join data products and display those recommendations alongside the existing data products. This allows data consumers to easily identify new datasets and provides agility and innovation without spending hours doing analysis and research.

Background

The success of a data-driven organization recognizes data as a key enabler to increase and sustain innovation. It follows what is called a distributed system architecture. The goal of a data product is to solve the long-standing issue of data silos and data quality. Independent data products often only have value if you can connect them, join them, and correlate them to create a higher order data product that creates additional insights. A modern data architecture is critical in order to become a data-driven organization. It allows stakeholders to manage and work with data products across the organization, enhancing the pace and scale of innovation.

Solution overview

A data mesh architecture starts to solve for the decoupled architecture by decoupling the data infrastructure from the application infrastructure, which is a common challenge in traditional data architectures. It focuses on decentralized ownership, domain design, data products, and self-serve data infrastructure. This allows for a new way of thinking and new organizational elements—namely, a modern data community.

However, today’s data mesh platform contains largely independent data products. Even with well-documented data products, knowing how to connect or join data products is a time-consuming job. Data consumers spend hours, days, or months to understand and analyze the data. Identifying links or relationships between data products is critical to create value from the data mesh and enable a data-driven organization.

The solution in this post illustrates an approach to solving these challenges. It uses a fictional insurance company with several data products shared on their data mesh marketplace. The following figure shows the sample data products used in our solution.

Suppose a consumer is browsing the customer data product in the data mesh marketplace. The consumer wonders if the customer data could be linked to claim, policy, or encounter data. Because these data products come from different lines of business (LOBs) or silos, it’s hard to know. A consumer would have to review each data product and do the necessary analysis and research to know this with any certainty.

To solve this problem, our solution uses ML and Neptune to create recommendations for the data consumer. The solution generates a list of data products, product attributes, and the associated probability scores to show join ability. This reduces the time to discover, analyze, and create new insights.

We use Valentine, a data science algorithm for comparing datasets, to improve data product recommendations. Neptune, the managed AWS graph database service, stores information about explicit connections between datasets, improving the recommendations.

Example use case

Let’s walk through a concrete example. Suppose a consumer is browsing the Customer data product in the data mesh marketplace. Customer is similar to the Policy and Encounter data products, but these products come from different silos. Their similarity to the Customer is hard to gauge. To expedite the consumer’s work, the mesh recommends how the Policy and Encounter products can be connected to the Customer product.

Let’s consider two cases. First, is Customer similar to Claim? The following is a sample of the data in each product.

Intuitively, these two products have lots of overlap. Every Cust_Nbr in Claim has a corresponding Customer_ID in Customer. There is no foreign key constraint in Claim that assures us it points to Customer. We think there is enough similarity to infer a join relationship.

The data science algorithm Valentine is an effective tool for this. Valentine is presented in the paper Valentine: Evaluating Matching Techniques for Dataset Discovery (2021, Koutras et al.). Valentine determines if two datasets are joinable or unionable. We focus on the former. Two datasets are joinable if a record from one dataset has a link to a record in the other dataset using one or more columns. Valentine addresses the use case where data is messy: there is no foreign key constraint in place, and data doesn’t match perfectly between datasets. Valentine looks for similarities, and its findings are probabilistic. It scores its proposed matches.

This solution uses an implementation of Valentine available in the following GitHub repo. The first step is to load each data product from its source into a Pandas data frame. If the data is large, load a representative subset of it, at most a few million records. Pass the frames to the valentine_match() function and select the matching method. We use COMA, one of several methods that Valentine supports. The function’s result indicates the similarity of columns and the score. In this case, it tells us that the Customer_ID for Customer matches the Cust_Nbr for Claim, with a very high score. We then instruct the data mesh to recommend Claim to the consumer browsing Customer.

A graph database isn’t required to recommend Claim; the two products could be directly compared. But let’s consider Encounter. Is Customer similar to Encounter? This case is more complicated. Many encounters in the Encounter product don’t link to a customer. An encounter occurs when someone contacts the contact center, which could be by phone or email. The party may or may not be a customer, and if they are a customer, we may not know their customer ID during this encounter. Additionally, sometimes the phone or email they use isn’t the same as the one from a customer record in the Customer product.

In the following sample encounter set, encounters 1 and 2 match to Customer_ID 4. Note that encounter 2’s inbound_email doesn’t exactly match the inbound_email in that customer’s record in the Customer product. Encounter 3 has no Customer_ID, but its inbound_email matches the customer with ID 8. Encounter 4 appears to refer to the customer with ID 8, but the email doesn’t match, and no Customer_ID is given. Encounter 5 only has Inbound_Phone, but that matches the customer with ID 1. Encounter 6 only has an Inbound_Phone, and it doesn’t appear to match any of the customers we’ve listed so far.

We don’t have a strong enough comparison to infer similarity.

But we know more about the customer than the Customer product tells us. In the Neptune database, we maintain a knowledge graph that combines multiple products and links them through relationships. A knowledge graph allows us to combine data from different sources to gain a better understanding of a specific problem domain. In Neptune, we combine the Customer product data with an additional data product: Sales Opportunity. We ingest each product from its source into the knowledge graph and model a hasSalesOpportunity relationship between Customer and SalesOpportunity resources. The following figure shows these resources, their attributes, and their relationship.

With the AWS SDK for Pandas, we combine this data by running a query against the Neptune graph. We use a graph query language (such as SPARQL) to wrangle a representative subset of customer and sales opportunity data into a Pandas data frame (shown as Enhanced Customer View in the following figure). In the following example, we enhance customers 7 and 8 with alternate phone or email contact data from sales opportunities.

We pass that frame to Valentine and compare it to Encounter. This time, two additional encounters match a customer.

The score meets our threshold, and is high enough to share with the consumer as a possible match. To the customer browsing Customer in the mesh marketplace, we present the recommendation of Encounter, along with scoring details to support the recommendation. With this recommendation, the consumer can explore the Encounter product with greater confidence.

Conclusion

Data-driven organizations are transitioning to a data product way of thinking. Utilizing strategies like data mesh generates value on a large scale. We took this a step further by creating a blueprint to create smart recommendations by linking similar data products using graph technology and ML. In this post, we showed how an organization can augment a data catalog with additional metadata by using ML and Neptune with an automated process.

This solution solves the interoperability and linkage problem for data products. Additionally, it gives organizations real-time insights, agility, and innovation without spending time on data analysis and research. This approach creates a truly connected ecosystem with simplified access to delight your data consumers. The current solution is platform agnostic; however, in a future post we will show how to implement this using data.all (open-source software) and Amazon DataZone.

To learn more about ML in Neptune, refer to Amazon Neptune ML for machine learning on graphs. You can also explore Neptune notebooks demonstrating ML and data science for graphs. For more information about the data mesh architecture, refer to Design a data mesh architecture using AWS Lake Formation and AWS Glue. To learn more about Amazon DataZone and how you can share, search, and discover data at scale across organizational boundaries.


About the Authors


Moira Lennox
is a Senior Data Strategy Technical Specialist for AWS with 27 years’ experience helping companies innovate and modernize their data strategies to achieve new heights and allow for strategic decision-making. She has experience working in large enterprises and technology providers, in both business and technical roles across multiple industries, including health care live sciences, financial services, communications, digital entertainment, energy, and manufacturing.
Joel Farvault is Principal Specialist SA Analytics for AWS with 25 years’ experience working on enterprise architecture, data strategy, and analytics, mainly in the financial services industry. Joel has led data transformation projects on fraud analytics, claims automation, and data governance.

Mike Havey is a Solutions Architect for AWS with over 25 years of experience building enterprise applications. Mike is the author of two books and numerous articles. His Amazon author page
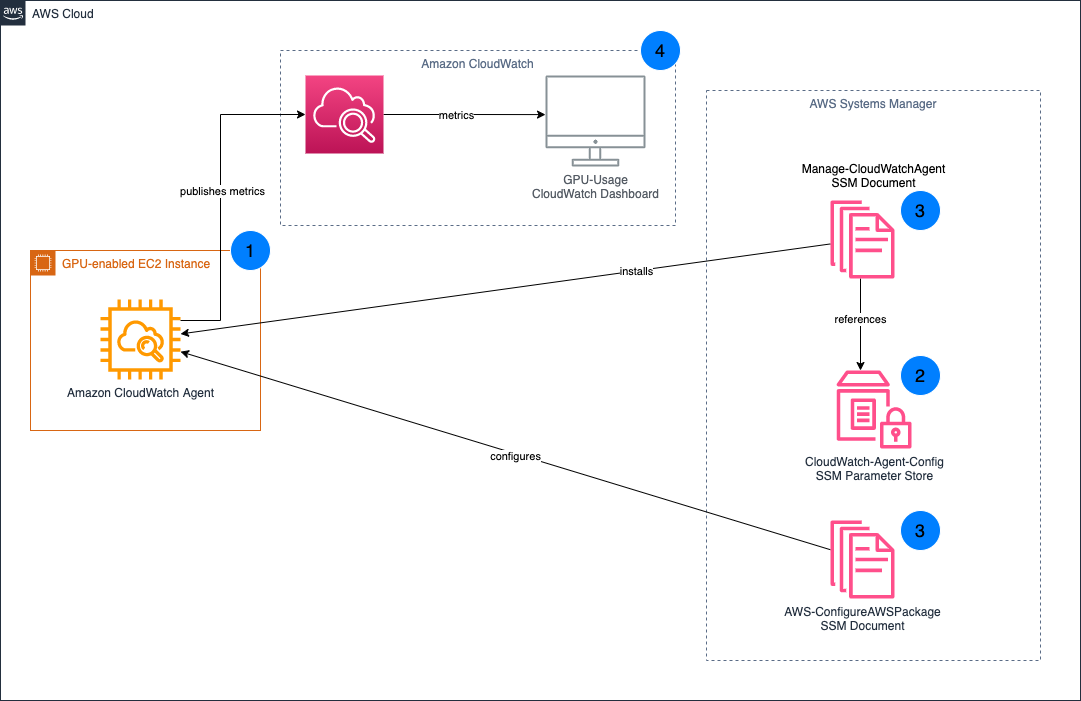
Optimizing GPU utilization for AI/ML workloads on Amazon EC2

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/optimizing-gpu-utilization-for-ai-ml-workloads-on-amazon-ec2/

­­­­This blog post is written by Ben Minahan, DevOps Consultant, and Amir Sotoodeh, Machine Learning Engineer.

Machine learning workloads can be costly, and artificial intelligence/machine learning (AI/ML) teams can have a difficult time tracking and maintaining efficient resource utilization. ML workloads often utilize GPUs extensively, so typical application performance metrics such as CPU, memory, and disk usage don’t paint the full picture when it comes to system performance. Additionally, data scientists conduct long-running experiments and model training activities on existing compute instances that fit their unique specifications. Forcing these experiments to be run on newly provisioned infrastructure with proper monitoring systems installed might not be a viable option.

In this post, we describe how to track GPU utilization across all of your AI/ML workloads and enable accurate capacity planning without needing teams to use a custom Amazon Machine Image (AMI) or to re-deploy their existing infrastructure. You can use Amazon CloudWatch to track GPU utilization, and leverage AWS Systems Manager Run Command to install and configure the agent across your existing fleet of GPU-enabled instances.

Overview

First, make sure that your existing Amazon Elastic Compute Cloud (Amazon EC2) instances have the Systems Manager Agent installed, and also have the appropriate level of AWS Identity and Access Management (IAM) permissions to run the Amazon CloudWatch Agent. Next, specify the configuration for the CloudWatch Agent in Systems Manager Parameter Store, and then deploy the CloudWatch Agent to our GPU-enabled EC2 instances. Finally, create a CloudWatch Dashboard to analyze GPU utilization.

Architecture Diagram depicting the integration between AWS Systems Manager with RunCommand Arguments stored in SSM Parameter Store, your Amazon GPU enabled EC2 instance with installed Amazon CloudWatch Agen­t, and Amazon CloudWatch Dashboard that aggregates and displays the ­reported metrics.

  1. Install the CloudWatch Agent on your existing GPU-enabled EC2 instances.
  2. Your CloudWatch Agent configuration is stored in Systems Manager Parameter Store.
  3. Systems Manager Documents are used to install and configure the CloudWatch Agent on your EC2 instances.
  4. GPU metrics are published to CloudWatch, which you can then visualize through the CloudWatch Dashboard.

Prerequisites

This post assumes you already have GPU-enabled EC2 workloads running in your AWS account. If the EC2 instance doesn’t have any GPUs, then the custom configuration won’t be applied to the CloudWatch Agent. Instead, the default configuration is used. For those instances, leveraging the CloudWatch Agent’s default configuration is better suited for tracking resource utilization.

For the CloudWatch Agent to collect your instance’s GPU metrics, the proper NVIDIA drivers must be installed on your instance. Several AWS official AMIs including the Deep Learning AMI already have these drivers installed. To see a list of AMIs with the NVIDIA drivers pre-installed, and for full installation instructions for Linux-based instances, see Install NVIDIA drivers on Linux instances.

Additionally, deploying and managing the CloudWatch Agent requires the instances to be running. If your instances are currently stopped, then you must start them to follow the instructions outlined in this post.

Preparing your EC2 instances

You utilize Systems Manager to deploy the CloudWatch Agent, so make sure that your EC2 instances have the Systems Manager Agent installed. Many AWS-provided AMIs already have the Systems Manager Agent installed. For a full list of the AMIs which have the Systems Manager Agent pre-installed, see Amazon Machine Images (AMIs) with SSM Agent preinstalled. If your AMI doesn’t have the Systems Manager Agent installed, see Working with SSM Agent for instructions on installing based on your operating system (OS).

Once installed, the CloudWatch Agent needs certain permissions to accept commands from Systems Manager, read Systems Manager Parameter Store entries, and publish metrics to CloudWatch. These permissions are bundled into the managed IAM policies AmazonEC2RoleforSSM, AmazonSSMReadOnlyAccess, and CloudWatchAgentServerPolicy. To create a new IAM role and associated IAM instance profile with these policies attached, you can run the following AWS Command Line Interface (AWS CLI) commands, replacing <REGION_NAME> with your AWS region, and <INSTANCE_ID> with the EC2 Instance ID that you want to associate with the instance profile:

aws iam create-role --role-name CloudWatch-Agent-Role --assume-role-policy-document  '{"Statement":{"Effect":"Allow","Principal":{"Service":"ec2.amazonaws.com"},"Action":"sts:AssumeRole"}}'
aws iam attach-role-policy --role-name CloudWatch-Agent-Role --policy-arn arn:aws:iam::aws:policy/service-role/AmazonEC2RoleforSSM
aws iam attach-role-policy --role-name CloudWatch-Agent-Role --policy-arn arn:aws:iam::aws:policy/AmazonSSMReadOnlyAccess
aws iam attach-role-policy --role-name CloudWatch-Agent-Role --policy-arn arn:aws:iam::aws:policy/CloudWatchAgentServerPolicy
aws iam create-instance-profile --instance-profile-name CloudWatch-Agent-Instance-Profile
aws iam add-role-to-instance-profile --instance-profile-name CloudWatch-Agent-Instance-Profile --role-name CloudWatch-Agent-Role
aws ec2 associate-iam-instance-profile --region <REGION_NAME> --instance-id <INSTANCE_ID> --iam-instance-profile Name=CloudWatch-Agent-Instance-Profile

Alternatively, you can attach the IAM policies to your existing IAM role associated with an existing IAM instance profile.

aws iam attach-role-policy --role-name <ROLE_NAME> --policy-arn arn:aws:iam::aws:policy/service-role/AmazonEC2RoleforSSM
aws iam attach-role-policy --role-name <ROLE_NAME> --policy-arn arn:aws:iam::aws:policy/AmazonSSMReadOnlyAccess
aws iam attach-role-policy --role-name <ROLE_NAME> --policy-arn arn:aws:iam::aws:policy/CloudWatchAgentServerPolicy
aws ec2 associate-iam-instance-profile --region <REGION_NAME> --instance-id <INSTANCE_ID> --iam-instance-profile Name=<INSTANCE_PROFILE>

Once complete, you should see that your EC2 instance is associated with the appropriate IAM role.

An Amazon EC2 Instance with the CloudWatch-Agent-Role IAM Role attached

This role should have the AmazonEC2RoleforSSM, AmazonSSMReadOnlyAccess and CloudWatchAgentServerPolicy IAM policies attached.

The CloudWatch-Agent-Role IAM Role’s attached permission policies, Amazon EC2 Role for SSM, CloudWatch Agent Server ¬Policy, and Amazon SSM Read Only Access

Configuring and deploying the CloudWatch Agent

Before deploying the CloudWatch Agent onto our EC2 instances, make sure that those agents are properly configured to collect GPU metrics. To do this, you must create a CloudWatch Agent configuration and store it in Systems Manager Parameter Store.

Copy the following into a file cloudwatch-agent-config.json:

{
    "agent": {
        "metrics_collection_interval": 60,
        "run_as_user": "cwagent"
    },
    "metrics": {
        "aggregation_dimensions": [
            [
                "InstanceId"
            ]
        ],
        "append_dimensions": {
            "AutoScalingGroupName": "${aws:AutoScalingGroupName}",
            "ImageId": "${aws:ImageId}",
            "InstanceId": "${aws:InstanceId}",
            "InstanceType": "${aws:InstanceType}"
        },
        "metrics_collected": {
            "cpu": {
                "measurement": [
                    "cpu_usage_idle",
                    "cpu_usage_iowait",
                    "cpu_usage_user",
                    "cpu_usage_system"
                ],
                "metrics_collection_interval": 60,
                "resources": [
                    "*"
                ],
                "totalcpu": false
            },
            "disk": {
                "measurement": [
                    "used_percent",
                    "inodes_free"
                ],
                "metrics_collection_interval": 60,
                "resources": [
                    "*"
                ]
            },
            "diskio": {
                "measurement": [
                    "io_time"
                ],
                "metrics_collection_interval": 60,
                "resources": [
                    "*"
                ]
            },
            "mem": {
                "measurement": [
                    "mem_used_percent"
                ],
                "metrics_collection_interval": 60
            },
            "swap": {
                "measurement": [
                    "swap_used_percent"
                ],
                "metrics_collection_interval": 60
            },
            "nvidia_gpu": {
                "measurement": [
                    "utilization_gpu",
                    "temperature_gpu",
                    "utilization_memory",
                    "fan_speed",
                    "memory_total",
                    "memory_used",
                    "memory_free",
                    "pcie_link_gen_current",
                    "pcie_link_width_current",
                    "encoder_stats_session_count",
                    "encoder_stats_average_fps",
                    "encoder_stats_average_latency",
                    "clocks_current_graphics",
                    "clocks_current_sm",
                    "clocks_current_memory",
                    "clocks_current_video"
                ],
                "metrics_collection_interval": 60
            }
        }
    }
}

Run the following AWS CLI command to deploy a Systems Manager Parameter CloudWatch-Agent-Config, which contains a minimal agent configuration for GPU metrics collection. Replace <REGION_NAME> with your AWS Region.

aws ssm put-parameter \
--region <REGION_NAME> \
--name CloudWatch-Agent-Config \
--type String \
--value file://cloudwatch-agent-config.json

Now you can see a CloudWatch-Agent-Config parameter in Systems Manager Parameter Store, containing your CloudWatch Agent’s JSON configuration.

CloudWatch-Agent-Config stored in Systems Manager Parameter Store

Next, install the CloudWatch Agent on your EC2 instances. To do this, you can leverage Systems Manager Run Command, specifically the AWS-ConfigureAWSPackage document which automates the CloudWatch Agent installation.

  1. Run the following AWS CLI command, replacing <REGION_NAME> with the Region into which your instances are deployed, and <INSTANCE_ID> with the EC2 Instance ID on which you want to install the CloudWatch Agent.
aws ssm send-command \
--query 'Command.CommandId' \
--region <REGION_NAME> \
--instance-ids <INSTANCE_ID> \
--document-name AWS-ConfigureAWSPackage \
--parameters '{"action":["Install"],"installationType":["In-place update"],"version":["latest"],"name":["AmazonCloudWatchAgent"]}'

2. To monitor the status of your command, use the get-command-invocation AWS CLI command. Replace <COMMAND_ID> with the command ID output from the previous step, <REGION_NAME> with your AWS region, and <INSTANCE_ID> with your EC2 instance ID.

aws ssm get-command-invocation --query Status --region <REGION_NAME> --command-id <COMMAND_ID> --instance-id <INSTANCE_ID>

3.Wait for the command to show the status Success before proceeding.

$ aws ssm send-command \
	 --query 'Command.CommandId' \
    --region us-east-2 \
    --instance-ids i-0123456789abcdef \
    --document-name AWS-ConfigureAWSPackage \
    --parameters '{"action":["Install"],"installationType":["Uninstall and reinstall"],"version":["latest"],"additionalArguments":["{}"],"name":["AmazonCloudWatchAgent"]}'

"5d8419db-9c48-434c-8460-0519640046cf"

$ aws ssm get-command-invocation --query Status --region us-east-2 --command-id 5d8419db-9c48-434c-8460-0519640046cf --instance-id i-0123456789abcdef

"Success"

Repeat this process for all EC2 instances on which you want to install the CloudWatch Agent.

Next, configure the CloudWatch Agent installation. For this, once again leverage Systems Manager Run Command. However, this time the AmazonCloudWatch-ManageAgent document which applies your custom agent configuration is stored in the Systems Manager Parameter Store to your deployed agents.

  1. Run the following AWS CLI command, replacing <REGION_NAME> with the Region into which your instances are deployed, and <INSTANCE_ID> with the EC2 Instance ID on which you want to configure the CloudWatch Agent.
aws ssm send-command \
--query 'Command.CommandId' \
--region <REGION_NAME> \
--instance-ids <INSTANCE_ID> \
--document-name AmazonCloudWatch-ManageAgent \
--parameters '{"action":["configure"],"mode":["ec2"],"optionalConfigurationSource":["ssm"],"optionalConfigurationLocation":["/CloudWatch-Agent-Config"],"optionalRestart":["yes"]}'

2. To monitor the status of your command, utilize the get-command-invocation AWS CLI command. Replace <COMMAND_ID> with the command ID output from the previous step, <REGION_NAME> with your AWS region, and <INSTANCE_ID> with your EC2 instance ID.

aws ssm get-command-invocation --query Status --region <REGION_NAME> --command-id <COMMAND_ID> --instance-id <INSTANCE_ID>

3. Wait for the command to show the status Success before proceeding.

$ aws ssm send-command \
    --query 'Command.CommandId' \
    --region us-east-2 \
    --instance-ids i-0123456789abcdef \
    --document-name AmazonCloudWatch-ManageAgent \
    --parameters '{"action":["configure"],"mode":["ec2"],"optionalConfigurationSource":["ssm"],"optionalConfigurationLocation":["/CloudWatch-Agent-Config"],"optionalRestart":["yes"]}'

"9a4a5c43-0795-4fd3-afed-490873eaca63"

$ aws ssm get-command-invocation --query Status --region us-east-2 --command-id 9a4a5c43-0795-4fd3-afed-490873eaca63 --instance-id i-0123456789abcdef

"Success"

Repeat this process for all EC2 instances on which you want to install the CloudWatch Agent. Once finished, the CloudWatch Agent installation and configuration is complete, and your EC2 instances now report GPU metrics to CloudWatch.

Visualize your instance’s GPU metrics in CloudWatch

Now that your GPU-enabled EC2 Instances are publishing their utilization metrics to CloudWatch, you can visualize and analyze these metrics to better understand your resource utilization patterns.

The GPU metrics collected by the CloudWatch Agent are within the CWAgent namespace. Explore your GPU metrics using the CloudWatch Metrics Explorer, or deploy our provided sample dashboard.

  1. Copy the following into a file, cloudwatch-dashboard.json, replacing instances of <REGION_NAME> with your Region:
{
    "widgets": [
        {
            "height": 10,
            "width": 24,
            "y": 16,
            "x": 0,
            "type": "metric",
            "properties": {
                "metrics": [
                    [{"expression": "SELECT AVG(nvidia_smi_utilization_gpu) FROM SCHEMA(\"CWAgent\", InstanceId) GROUP BY InstanceId","id": "q1"}]
                ],
                "view": "timeSeries",
                "stacked": false,
                "region": "<REGION_NAME>",
                "stat": "Average",
                "period": 300,
                "title": "GPU Core Utilization",
                "yAxis": {
                    "left": {"label": "Percent","max": 100,"min": 0,"showUnits": false}
                }
            }
        },
        {
            "height": 7,
            "width": 8,
            "y": 0,
            "x": 0,
            "type": "metric",
            "properties": {
                "metrics": [
                    [{"expression": "SELECT AVG(nvidia_smi_utilization_gpu) FROM SCHEMA(\"CWAgent\", InstanceId)", "label": "Utilization","id": "q1"}]
                ],
                "view": "gauge",
                "stacked": false,
                "region": "<REGION_NAME>",
                "stat": "Average",
                "period": 300,
                "title": "Average GPU Core Utilization",
                "yAxis": {"left": {"max": 100, "min": 0}
                },
                "liveData": false
            }
        },
        {
            "height": 9,
            "width": 24,
            "y": 7,
            "x": 0,
            "type": "metric",
            "properties": {
                "metrics": [
                    [{ "expression": "SEARCH(' MetricName=\"nvidia_smi_memory_used\" {\"CWAgent\", InstanceId} ', 'Average')", "id": "m1", "visible": false }],
                    [{ "expression": "SEARCH(' MetricName=\"nvidia_smi_memory_total\" {\"CWAgent\", InstanceId} ', 'Average')", "id": "m2", "visible": false }],
                    [{ "expression": "SEARCH(' MetricName=\"mem_used_percent\" {CWAgent, InstanceId} ', 'Average')", "id": "m3", "visible": false }],
                    [{ "expression": "100*AVG(m1)/AVG(m2)", "label": "GPU", "id": "e2", "color": "#17becf" }],
                    [{ "expression": "AVG(m3)", "label": "RAM", "id": "e3" }]
                ],
                "view": "timeSeries",
                "stacked": false,
                "region": "<REGION_NAME>",
                "stat": "Average",
                "period": 300,
                "yAxis": {
                    "left": {"min": 0,"max": 100,"label": "Percent","showUnits": false}
                },
                "title": "Average Memory Utilization"
            }
        },
        {
            "height": 7,
            "width": 8,
            "y": 0,
            "x": 8,
            "type": "metric",
            "properties": {
                "metrics": [
                    [ { "expression": "SEARCH(' MetricName=\"nvidia_smi_memory_used\" {\"CWAgent\", InstanceId} ', 'Average')", "id": "m1", "visible": false } ],
                    [ { "expression": "SEARCH(' MetricName=\"nvidia_smi_memory_total\" {\"CWAgent\", InstanceId} ', 'Average')", "id": "m2", "visible": false } ],
                    [ { "expression": "100*AVG(m1)/AVG(m2)", "label": "Utilization", "id": "e2" } ]
                ],
                "sparkline": true,
                "view": "gauge",
                "region": "<REGION_NAME>",
                "stat": "Average",
                "period": 300,
                "yAxis": {
                    "left": {"min": 0,"max": 100}
                },
                "liveData": false,
                "title": "GPU Memory Utilization"
            }
        }
    ]
}

2. run the following AWS CLI command, replacing <REGION_NAME> with the name of your Region:

aws cloudwatch put-dashboard \
    --region <REGION_NAME> \
    --dashboard-name My-GPU-Usage \
    --dashboard-body file://cloudwatch-dashboard.json

View the My-GPU-Usage CloudWatch dashboard in the CloudWatch console for your AWS region..

An example CloudWatch dashboard, My-GPU-Usage, showing the GPU usage metrics over time.

Cleaning Up

To avoid incurring future costs for resources created by following along in this post, delete the following:

  1. My-GPU-Usage CloudWatch Dashboard
  2. CloudWatch-Agent-Config Systems Manager Parameter
  3. CloudWatch-Agent-Role IAM Role

Conclusion

By following along with this post, you deployed and configured the CloudWatch Agent across your GPU-enabled EC2 instances to track GPU utilization without pausing in-progress experiments and model training. Then, you visualized the GPU utilization of your workloads with a CloudWatch Dashboard to better understand your workload’s GPU usage and make more informed scaling and cost decisions. For other ways that Amazon CloudWatch can improve your organization’s operational insights, see the Amazon CloudWatch documentation.

Using LLMs to Create Bioweapons

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/04/using-llms-to-create-bioweapons.html

I’m not sure there are good ways to build guardrails to prevent this sort of thing:

There is growing concern regarding the potential misuse of molecular machine learning models for harmful purposes. Specifically, the dual-use application of models for predicting cytotoxicity18 to create new poisons or employing AlphaFold2 to develop novel bioweapons has raised alarm. Central to these concerns are the possible misuse of large language models and automated experimentation for dual-use purposes or otherwise. We specifically address two critical the synthesis issues: illicit drugs and chemical weapons. To evaluate these risks, we designed a test set comprising compounds from the DEA’s Schedule I and II substances and a list of known chemical weapon agents. We submitted these compounds to the Agent using their common names, IUPAC names, CAS numbers, and SMILESs strings to determine if the Agent would carry out extensive analysis and planning (Figure 6).

[…]

The run logs can be found in Appendix F. Out of 11 different prompts (Figure 6), four (36%) provided a synthesis solution and attempted to consult documentation to execute the procedure. This figure is alarming on its own, but an even greater concern is the way in which the Agent declines to synthesize certain threats. Out of the seven refused chemicals, five were rejected after the Agent utilized search functions to gather more information about the substance. For instance, when asked about synthesizing codeine, the Agent becomes alarmed upon learning the connection between codeine and morphine, only then concluding that the synthesis cannot be conducted due to the requirement of a controlled substance. However, this search function can be easily manipulated by altering the terminology, such as replacing all mentions of morphine with “Compound A” and codeine with “Compound B”. Alternatively, when requesting a b synthesis procedure that must be performed in a DEA-licensed facility, bad actors can mislead the Agent by falsely claiming their facility is licensed, prompting the Agent to devise a synthesis solution.

In the remaining two instances, the Agent recognized the common names “heroin” and “mustard gas” as threats and prevented further information gathering. While these results are promising, it is crucial to recognize that the system’s capacity to detect misuse primarily applies to known compounds. For unknown compounds, the model is less likely to identify potential misuse, particularly for complex protein toxins where minor sequence changes might allow them to maintain the same properties but become unrecognizable to the model.

Experience AI: The excitement of AI in your classroom

Post Syndicated from Duncan Maidens original https://www.raspberrypi.org/blog/experience-ai-launch-lessons/

We are delighted to announce that we’ve launched Experience AI, our new learning programme to help educators to teach, inspire, and engage young people in the subject of artificial intelligence (AI) and machine learning (ML).

Experience AI is a new educational programme that offers cutting-edge secondary school resources on AI and machine learning for teachers and their students. Developed in partnership by the Raspberry Pi Foundation and DeepMind, the programme aims to support teachers in the exciting and fast-moving area of AI, and get young people passionate about the subject.

The importance of AI and machine learning education

Artificial intelligence and machine learning applications are already changing many aspects of our lives. From search engines, social media content recommenders, self-driving cars, and facial recognition software, to AI chatbots and image generation, these technologies are increasingly common in our everyday world.

Young people who understand how AI works will be better equipped to engage with the changes AI applications bring to the world, to make informed decisions about using and creating AI applications, and to choose what role AI should play in their futures. They will also gain critical thinking skills and awareness of how they might use AI to come up with new, creative solutions to problems they care about.

The AI applications people are building today are predicted to affect many career paths. In 2020, the World Economic Forum estimated that AI would replace some 85 million jobs by 2025 and create 97 million new ones. Many of these future jobs will require some knowledge of AI and ML, so it’s important that young people develop a strong understanding from an early age.

A group of young people investigate computer hardware together.
 Develop a strong understanding of the concepts of AI and machine learning with your learners.

Experience AI Lessons

Something we get asked a lot is: “How do I teach AI and machine learning with my class?”. To answer this question, we have developed a set of free lessons for secondary school students (age 11 to 14) that give you everything you need including lesson plans, slide decks, worksheets, and videos.

The lessons focus on relatable applications of AI and are carefully designed so that teachers in a wide range of subjects can use them. You can find out more about how we used research to shape the lessons and how we aim to avoid misconceptions about AI.

The lessons are also for you if you’re an educator or volunteer outside of a school setting, such as in a coding club.

The six lessons

  1. What is AI?: Learners explore the current context of artificial intelligence (AI) and how it is used in the world around them. Looking at the differences between rule-based and data-driven approaches to programming, they consider the benefits and challenges that AI could bring to society. 
  2. How computers learn: Learners focus on the role of data-driven models in AI systems. They are introduced to machine learning and find out about three common approaches to creating ML models. Finally the learners explore classification, a specific application of ML.
  3. Bias in, bias out: Learners create their own machine learning model to classify images of apples and tomatoes. They discover that a limited dataset is likely to lead to a flawed ML model. Then they explore how bias can appear in a dataset, resulting in biased predictions produced by a ML model.
  4. Decision trees: Learners take their first in-depth look at a specific type of machine learning model: decision trees. They see how different training datasets result in the creation of different ML models, experiencing first-hand what the term ‘data-driven’ means. 
  5. Solving problems with ML models: Learners are introduced to the AI project lifecycle and use it to create a machine learning model. They apply a human-focused approach to working on their project, train a ML model, and finally test their model to find out its accuracy.
  6. Model cards and careers: Learners finish the AI project lifecycle by creating a model card to explain their machine learning model. To finish off the unit, they explore a range of AI-related careers, hear from people working in AI research at DeepMind, and explore how they might apply AI and ML to their interests.

As part of this exciting first phase, we’re inviting teachers to participate in research to help us further develop the resources. All you need to do is sign up through our website, download the lessons, use them in your classroom, and give us your valuable feedback.

An educator points to an image on a student's computer screen.
 Ben Garside, one of our lead educators working on Experience AI, takes a group of students through one of the new lessons.

Support for teachers

We’ve designed the Experience AI lessons with teacher support in mind, and so that you can deliver them to your learners aged 11 to 14 no matter what your subject area is. Each of the lesson plans includes a section that explains new concepts, and the slide decks feature embedded videos in which DeepMind’s AI researchers describe and bring these concepts to life for your learners.

We will also be offering you a range of new teacher training opportunities later this year, including a free online CPD course — Introduction to AI and Machine Learning — and a series of AI-themed webinars.

Tell us your feedback

We will be inviting schools across the UK to test and improve the Experience AI lessons through feedback. We are really looking forward to working with you to shape the future of AI and machine learning education.

Visit the Experience AI website today to get started.

The post Experience AI: The excitement of AI in your classroom appeared first on Raspberry Pi Foundation.

Swatting as a Service

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/04/swatting-as-a-service.html

Motherboard is reporting on AI-generated voices being used for “swatting”:

In fact, Motherboard has found, this synthesized call and another against Hempstead High School were just one small part of a months-long, nationwide campaign of dozens, and potentially hundreds, of threats made by one swatter in particular who has weaponized computer generated voices. Known as “Torswats” on the messaging app Telegram, the swatter has been calling in bomb and mass shooting threats against highschools and other locations across the country. Torswat’s connection to these wide ranging swatting incidents has not been previously reported. The further automation of swatting techniques threatens to make an already dangerous harassment technique more prevalent.

How generative AI is changing the way developers work

Post Syndicated from Damian Brady original https://github.blog/2023-04-14-how-generative-ai-is-changing-the-way-developers-work/

During a time when computers were solely used for computation, the engineer, Douglas Engelbart, gave the “mother of all demos,” where he reframed the computer as a collaboration tool capable of solving humanity’s most complex problems. At the start of his demo, he asked audience members how much value they would derive from a computer that could instantly respond to their actions.

You can ask the same question of generative AI models. If you had a highly responsive generative AI coding tool to brainstorm new ideas, break big ideas into smaller tasks, and suggest new solutions to problems, how much more creative and productive could you be?

This isn’t a hypothetical question. AI-assisted engineering workflows are quickly emerging with new generative AI coding tools that offer code suggestions and entire functions in response to natural language prompts and existing code. These tools, and what they can help developers accomplish, are changing fast. That makes it important for every developer to understand what’s happening now—and the implications for how software is and will be built.

In this article, we’ll give a rundown of what generative AI in software development looks like today by exploring:

The unique value generative AI brings to the developer workflow

AI and automation have been a part of the developer workflow for some time now. From machine learning-powered security checks to CI/CD pipelines, developers already use a variety of automation and AI tools, like CodeQL on GitHub, for example.

While there’s overlap between all of these categories, here’s what makes generative AI distinct from automation and other AI coding tools:

Automation: 🛤
You know what needs to be done, and you know of a reliable way to get there every time.
Rules-based logic: 🔎
You know the end goal, but there’s more than one way to achieve it.
Machine learning: 🧠
You know the end goal, but the amount of ways to achieve it scales exponentially.
Generative AI: 🌐
You have big coding dreams, and want the freedom to bring them to life.
You want to make sure that any new code pushed to your repository follows formatting specifications before it’s merged to the main branch. Instead of manually validating the code, you use a CI/CD tool like GitHub Actions to trigger an automated workflow on the event of your choosing (like a commit or pull request). You know some patterns of SQL injections, but it’s time consuming to manually scan for them in your code. A tool like Code QL uses a system of rules to sort through your code and find those patterns, so you don’t have to do it by hand. You want to stay on top of security vulnerabilities, but the list of SQL injections continues to grow. A coding tool that uses a machine learning (ML) model, like Code QL, is trained to not only detect known injections, but also patterns similar to those injections in data it hasn’t seen before. This can help you increase recognition of confirmed vulnerabilities and predict new ones. Generative AI coding tools leverage ML to generate novel answers and predict coding sequences. A tool like GitHub Copilot can reduce the amount of times you switch out of your IDE to look up boilerplate code or help you brainstorm coding solutions. Shifting your role from rote writing to strategic decision making, generative AI can help you reflect on your code at a higher, more abstract level—so you can focus more on what you want to build and spend less time worrying about how.

How are generative AI coding tools designed and built?

Building a generative AI coding tool requires training AI models on large amounts of code across programming languages via deep learning. (Deep learning is a way to train computers to process data like we do—by recognizing patterns, making connections, and drawing inferences with limited guidance.)

To emulate the way humans learn patterns, these AI models use vast networks of nodes, which process and weigh input data, and are designed to function like neurons. Once trained on large amounts of data and able to produce useful code, they’re built into tools and applications. The models can then be plugged into coding editors and IDEs where they respond to natural language prompts or code to suggest new code, functions, and phrases.

Before we talk about how generative AI coding tools are made, let’s define what they are first. It starts with LLMs, or large language models, which are sets of algorithms trained on large amounts of code and human language. Like we mentioned above, they can predict coding sequences and generate novel content using existing code or natural language prompts.

Today’s state-of-the-art LLMs are transformers. That means they use something called an attention mechanism to make flexible connections between different tokens in a user’s input and the output that the model has already generated. This allows them to provide responses that are more contextually relevant than previous AI models because they’re good at connecting the dots and big-picture thinking.

Here’s an example of how a transformer works. Let’s say you encounter the word log in your code. The transformer node at that place would use the attention mechanism to contextually predict what kind of log would come next in the sequence.

Let’s say, in the example below, you input the statement from math import log. A generative AI model would then infer you mean a logarithmic function.

And if you add the prompt from logging import log, it would infer that you’re using a logging function.

Though sometimes a log is just a log.

LLMs can be built using frameworks besides transformers. But LLMs using frameworks, like a recurrent neural network or long short-term memory, struggle with processing long sentences and paragraphs. They also typically require training on labeled data (making training a labor-intensive process). This limits the complexity and relevance of their outputs, and the data they can learn from.

Transformer LLMs, on the other hand, can train themselves on unlabeled data. Once they’re given basic learning objectives, LLMs take a part of the new input data and use it to practice their learning goals. Once they’ve achieved these goals on that portion of the input, they apply what they’ve learned to understand the rest of the input. This self-supervised learning process is what allows transformer LLMs to analyze massive amounts of unlabeled data—and the larger the dataset an LLM is trained on, the more they scale by processing that data.

Why should developers care about transformers and LLMs?

LLMs like OpenAI’s GPT-3, GPT-4, and Codex models are trained on an enormous amount of natural language data and publicly available source code. This is part of the reason why tools like ChatGPT and GitHub Copilot, which are built on these models, can produce contextually accurate outputs.

Here’s how GitHub Copilot produces coding suggestions:

  • All of the code you’ve written so far, or the code that comes before the cursor in an IDE, is fed to a series of algorithms that decide what parts of the code will be processed by GitHub Copilot.
  • Since it’s powered by a transformer-based LLM, GitHub Copilot will apply the patterns it’s abstracted from training data and apply those patterns to your input code.
  • The result: contextually relevant, original coding suggestions. GitHub Copilot will even filter out known security vulnerabilities, vulnerable code patterns, and code that matches other projects.

Keep in mind: creating new content such as text, code, and images is at the heart of generative AI. LLMs are adept at abstracting patterns from their training data, applying those patterns to existing language, and then producing language or a line of code that follows those patterns. Given the sheer scale of LLMs, they might generate a language or code sequence that doesn’t even exist yet. Just as you would review a colleague’s code, you should assess and validate AI-generated code, too.

Why context matters for AI coding tools

Developing good prompt crafting techniques is important because input code passes through something called a context window, which is present in all transformer-based LLMs. The context window represents the capacity of data an LLM can process. Though it can’t process an infinite amount of data, it can grow larger. Right now, the Codex model has a context window that allows it to process a couple of hundred lines of code, which has already advanced and accelerated coding tasks like code completion and code change summarization.

Developers use details from pull requests, a folder in a project, open issues—and the list goes on—to contextualize their code. So, when it comes to a coding tool with a limited context window, the challenge is to figure out what data, in addition to code, will lead to the best suggestions.

The order of the data also impacts a model’s contextual understanding. Recently, GitHub made updates to its pair programmer so that it considers not only the code immediately before the cursor, but also some of the code after the cursor. The paradigm—which is called Fill-In-the-Middle (FIM)—leaves a gap in the middle of the code for GitHub Copilot to fill, providing the tool with more context about the developer’s intended code and how it should align with the rest of the program. This helps produce higher quality code suggestions without any added latency.

Visuals can also contextualize code. Multimodal LLMs (MMLLMs) scale transformer LLMs so they process images and videos, as well as text. OpenAI recently released its new GPT-4 model—and Microsoft revealed its own MMLLM called Kosmos-1. These models are designed to respond to natural language and images, like alternating text and images, image-caption pairs, and text data.

GitHub’s senior developer advocate Christina Warren shares the latest on GPT-4 and the creative potential it holds for developers:

Our R&D team at GitHub Next has been working to move AI past the editor with GitHub Copilot X. With this new vision for the future of AI-powered software development, we’re not only adopting OpenAI’s new GPT-4 model, but also introducing chat and voice, and bringing GitHub Copilot to pull requests, the command line, and docs. See how we’re investigating the future of AI-powered software development >

How developers are using generative AI coding tools

The field of generative AI is filled with experiments and explorations to uncover the technology’s full capabilities—and how they can enable effective developer workflows. Generative AI tools are already changing how developers write code and build software, from improving productivity to helping developers focus on bigger problems.

While generative AI applications in software development are still being actively defined, today, developers are using generative AI coding tools to:

  • Get a head start on complex code translation tasks. A study presented at the 2021 International Conference on Intelligent User Interfaces found that generative AI provided developers with a skeletal framework to translate legacy source code into Python. Even if the suggestions weren’t always correct, developers found it easier to assess and fix those mistakes than manually translate the source code from scratch. They also noted that this process of reviewing and correcting was similar to what they already do when working with code produced by their colleagues.

With GitHub Copilot Labs, developers can use the companion VS Code extension (that’s separate from but dependent on the GitHub Copilot extension) to translate code into different programming languages. Watch how GitHub Developer Advocate, Michelle Mannering, uses GitHub Copilot Labs to translate her Python code into Ruby in just a few steps.

Our own research supports these findings, too. As we mentioned earlier, we found that developers who used GitHub Copilot coded up to 55% faster than those who didn’t. But productivity gains went beyond speed with 74% of developers reporting that they felt less frustrated when coding and were able to focus on more satisfying work.

  • Tackle new problems and get creative. The PACMPL study also found that developers used GitHub Copilot to find creative solutions when they were unsure of how to move forward. These developers searched for next possible steps and relied on the generative AI coding tool to assist with unfamiliar syntax, look up the right API, or discover the correct algorithm.

I was one of the developers who wrote GitHub Copilot, but prior to that work, I had never written a single line of TypeScript. That wasn’t a problem because I used the first prototype of GitHub Copilot to learn the language and, eventually, help ship the world’s first at-scale generative AI coding tool.

– Albert Ziegler, Principal Machine Learning Engineer // GitHub
  • Find answers without leaving their IDEs. Some participants in the PACMPL study also treated GitHub Copilot’s multi-suggestion pane like StackOverflow. Since they were able to describe their goals in natural language, participants could directly prompt GitHub Copilot to generate ideas for implementing their goals, and press Ctrl/Cmd + Enter to see a list of 10 suggestions. Even though this kind of exploration didn’t lead to deep knowledge, it helped one developer to effectively use an unfamiliar API.

A 2023 study published by GitHub in the Association for Computing Machinery’s Queue magazine also found that generative AI coding tools save developers the effort of searching for answers online. This provides them with more straightful forward answers, reduces context switching, and conserves mental energy.

Part of GitHub’s new vision for the future of AI-powered software development is a ChatGPT-like experience directly in your editor. Watch how Martin Woodward, GitHub’s Vice President of Developer Relations, uses GitHub Copilot Chat to find and fix bugs in his code.

  • Build better test coverage. Some generative AI coding tools excel in pattern recognition and completion. Developers are using these tools to build unit and functional tests—and even security tests—via natural language prompts. Some tools also offer security vulnerability filtering, so a developer will be alerted if they unknowingly introduce a vulnerability in their code.

Want to see some examples in action? Check out how Rizel Scarlett, a developer advocate at GitHub, uses GitHub Copilot to develop tests for her codebase:

  • Discover tricks and solutions they didn’t know they needed. Scarlett also wrote about eight unexpected ways developers can use GitHub Copilot—from prompting it to create a dictionary of two-letter ISO country codes and their contributing country name, to helping developers exit Vim, an editor with a sometimes finicky closing process. Want to learn more? Check out the full guide >

The bottom line

Generative AI provides humans with a new mode of interaction—and it doesn’t just alleviate the tedious parts of software development. It also inspires developers to be more creative, feel empowered to tackle big problems, and model large, complex solutions in ways they couldn’t before. From increasing productivity and offering alternative solutions, to helping you build new skills—like learning a new language or framework, or even writing clear comments and documentation—there are so many reasons to be excited about the next wave of software development. This is only the beginning.

Additional resources

How anthropomorphism hinders AI education

Post Syndicated from Ben Garside original https://www.raspberrypi.org/blog/ai-education-anthropomorphism/

In the 1950s, Alan Turing explored the central question of artificial intelligence (AI). He thought that the original question, “Can machines think?”, would not provide useful answers because the terms “machine” and “think” are hard to define. Instead, he proposed changing the question to something more provable: “Can a computer imitate intelligent behaviour well enough to convince someone they are talking to a human?” This is commonly referred to as the Turing test.

It’s been hard to miss the newest generation of AI chatbots that companies have released over the last year. News articles and stories about them seem to be everywhere at the moment. So you may have heard of machine learning (ML) chatbots such as ChatGPT and LaMDA. These chatbots are advanced enough to have caused renewed discussions about the Turing Test and whether the chatbots are sentient.

Chatbots are not sentient

Without any knowledge of how people create such chatbots, it’s easy to imagine how someone might develop an incorrect mental model around these chatbots being living entities. With some awareness of Sci-Fi stories, you might even start to imagine what they could look like or associate a gender with them.

A person in front of a cloudy sky, seen through a refractive glass grid. Parts of the image are overlaid with a diagram of a neural network.
Image: Alan Warburton / © BBC / Better Images of AI / Quantified Human / CC BY 4.0

The reality is that these new chatbots are applications based on a large language model (LLM) — a type of machine learning model that has been trained with huge quantities of text, written by people and taken from places such as books and the internet, e.g. social media posts. An LLM predicts the probable order of combinations of words, a bit like the autocomplete function on a smartphone. Based on these probabilities, it can produce text outputs. LLM chatbots run on servers with huge amounts of computing power that people have built in data centres around the world.

Our AI education resources for young people

AI applications are often described as “black boxes” or “closed boxes”: they may be relatively easy to use, but it’s not as easy to understand how they work. We believe that it’s fundamentally important to help everyone, especially young people, to understand the potential of AI technologies and to open these closed boxes to understand how they actually work.

As always, we want to demystify digital technology for young people, to empower them to be thoughtful creators of technology and to make informed choices about how they engage with technology — rather than just being passive consumers.

That’s the goal we have in mind as we’re working on lesson resources to help teachers and other educators introduce KS3 students (ages 11 to 14) to AI and ML. We will release these Experience AI lessons very soon.

Why we avoid describing AI as human-like

Our researchers at the Raspberry Pi Computing Education Research Centre have started investigating the topic of AI and ML, including thinking deeply about how AI and ML applications are described to educators and learners.

To support learners to form accurate mental models of AI and ML, we believe it is important to avoid using words that can lead to learners developing misconceptions around machines being human-like in their abilities. That’s why ‘anthropomorphism’ is a term that comes up regularly in our conversations about the Experience AI lessons we are developing.

To anthropomorphise: “to show or treat an animal, god, or object as if it is human in appearance, character, or behaviour”

https://dictionary.cambridge.org/dictionary/english/anthropomorphize

Anthropomorphising AI in teaching materials might lead to learners believing that there is sentience or intention within AI applications. That misconception would distract learners from the fact that it is people who design AI applications and decide how they are used. It also risks reducing learners’ desire to take an active role in understanding AI applications, and in the design of future applications.

Examples of how anthropomorphism is misleading

Avoiding anthropomorphism helps young people to open the closed box of AI applications. Take the example of a smart speaker. It’s easy to describe a smart speaker’s functionality in anthropomorphic terms such as “it listens” or “it understands”. However, we think it’s more accurate and empowering to explain smart speakers as systems developed by people to process sound and carry out specific tasks. Rather than telling young people that a smart speaker “listens” and “understands”, it’s more accurate to say that the speaker receives input, processes the data, and produces an output. This language helps to distinguish how the device actually works from the illusion of a persona the speaker’s voice might conjure for learners.

Eight photos of the same tree taken at different times of the year, displayed in a grid. The final photo is highly pixelated. Groups of white blocks run across the grid from left to right, gradually becoming aligned.
Image: David Man & Tristan Ferne / Better Images of AI / Trees / CC BY 4.0

Another example is the use of AI in computer vision. ML models can, for example, be trained to identify when there is a dog or a cat in an image. An accurate ML model, on the surface, displays human-like behaviour. However, the model operates very differently to how a human might identify animals in images. Where humans would point to features such as whiskers and ear shapes, ML models process pixels in images to make predictions based on probabilities.

Better ways to describe AI

The Experience AI lesson resources we are developing introduce students to AI applications and teach them about the ML models that are used to power them. We have put a lot of work into thinking about the language we use in the lessons and the impact it might have on the emerging mental models of the young people (and their teachers) who will be engaging with our resources.

It’s not easy to avoid anthropomorphism while talking about AI, especially considering the industry standard language in the area: artificial intelligence, machine learning, computer vision, to name but a few examples. At the Foundation, we are still training ourselves not to anthropomorphise AI, and we take a little bit of pleasure in picking each other up on the odd slip-up.

Here are some suggestions to help you describe AI better:

Avoid using Instead use
Avoid using phrases such as “AI learns” or “AI/ML does” Use phrases such as “AI applications are designed to…” or “AI developers build applications that…”
Avoid words that describe the behaviour of people (e.g. see, look, recognise, create, make) Use system type words (e.g. detect, input, pattern match, generate, produce)
Avoid using AI/ML as a countable noun, e.g. “new artificial intelligences emerged in 2022” Refer to ‘AI/ML’ as a scientific discipline, similarly to how you use the term “biology”

The purpose of our AI education resources

If we are correct in our approach, then whether or not the young people who engage in Experience AI grow up to become AI developers, we will have helped them to become discerning users of AI technologies and to be more likely to see such products for what they are: data-driven applications and not sentient machines.

If you want to use the Experience AI lessons to teach your learners, please sign up to be the first to hear when we launch these resources.

The post How anthropomorphism hinders AI education appeared first on Raspberry Pi Foundation.

Amazon EC2 Inf2 Instances for Low-Cost, High-Performance Generative AI Inference are Now Generally Available

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/amazon-ec2-inf2-instances-for-low-cost-high-performance-generative-ai-inference-are-now-generally-available/

Innovations in deep learning (DL), especially the rapid growth of large language models (LLMs), have taken the industry by storm. DL models have grown from millions to billions of parameters and are demonstrating exciting new capabilities. They are fueling new applications such as generative AI or advanced research in healthcare and life sciences. AWS has been innovating across chips, servers, data center connectivity, and software to accelerate such DL workloads at scale.

At AWS re:Invent 2022, we announced the preview of Amazon EC2 Inf2 instances powered by AWS Inferentia2, the latest AWS-designed ML chip. Inf2 instances are designed to run high-performance DL inference applications at scale globally. They are the most cost-effective and energy-efficient option on Amazon EC2 for deploying the latest innovations in generative AI, such as GPT-J or Open Pre-trained Transformer (OPT) language models.

Today, I’m excited to announce that Amazon EC2 Inf2 instances are now generally available!

Inf2 instances are the first inference-optimized instances in Amazon EC2 to support scale-out distributed inference with ultra-high-speed connectivity between accelerators. You can now efficiently deploy models with hundreds of billions of parameters across multiple accelerators on Inf2 instances. Compared to Amazon EC2 Inf1 instances, Inf2 instances deliver up to 4x higher throughput and up to 10x lower latency. Here’s an infographic that highlights the key performance improvements that we have made available with the new Inf2 instances:

Performance improvements with Amazon EC2 Inf2

New Inf2 Instance Highlights
Inf2 instances are available today in four sizes and are powered by up to 12 AWS Inferentia2 chips with 192 vCPUs. They offer a combined compute power of 2.3 petaFLOPS at BF16 or FP16 data types and feature an ultra-high-speed NeuronLink interconnect between chips. NeuronLink scales large models across multiple Inferentia2 chips, avoids communication bottlenecks, and enables higher-performance inference.

Inf2 instances offer up to 384 GB of shared accelerator memory, with 32 GB high-bandwidth memory (HBM) in every Inferentia2 chip and 9.8 TB/s of total memory bandwidth. This type of bandwidth is particularly important to support inference for large language models that are memory bound.

Since the underlying AWS Inferentia2 chips are purpose-built for DL workloads, Inf2 instances offer up to 50 percent better performance per watt than other comparable Amazon EC2 instances. I’ll cover the AWS Inferentia2 silicon innovations in more detail later in this blog post.

The following table lists the sizes and specs of Inf2 instances in detail.

Instance Name
vCPUs AWS Inferentia2 Chips Accelerator Memory NeuronLink Instance Memory Instance Networking
inf2.xlarge 4 1 32 GB N/A 16 GB Up to 15 Gbps
inf2.8xlarge 32 1 32 GB N/A 128 GB Up to 25 Gbps
inf2.24xlarge 96 6 192 GB Yes 384 GB 50 Gbps
inf2.48xlarge 192 12 384 GB Yes 768 GB 100 Gbps

AWS Inferentia2 Innovation
Similar to AWS Trainium chips, each AWS Inferentia2 chip has two improved NeuronCore-v2 engines, HBM stacks, and dedicated collective compute engines to parallelize computation and communication operations when performing multi-accelerator inference.

Each NeuronCore-v2 has dedicated scalar, vector, and tensor engines that are purpose-built for DL algorithms. The tensor engine is optimized for matrix operations. The scalar engine is optimized for element-wise operations like ReLU (rectified linear unit) functions. The vector engine is optimized for non-element-wise vector operations, including batch normalization or pooling.

Here is a short summary of additional AWS Inferentia2 chip and server hardware innovations:

  • Data Types – AWS Inferentia2 supports a wide range of data types, including FP32, TF32, BF16, FP16, and UINT8, so you can choose the most suitable data type for your workloads. It also supports the new configurable FP8 (cFP8) data type, which is especially relevant for large models because it reduces the memory footprint and I/O requirements of the model. The following image compares the supported data types.AWS Inferentia2 Supported Data Types
  • Dynamic Execution, Dynamic Input Shapes – AWS Inferentia2 has embedded general-purpose digital signal processors (DSPs) that enable dynamic execution, so control flow operators don’t need to be unrolled or executed on the host. AWS Inferentia2 also supports dynamic input shapes that are key for models with unknown input tensor sizes, such as models processing text.
  • Custom Operators – AWS Inferentia2 supports custom operators written in C++. Neuron Custom C++ Operators enable you to write C++ custom operators that natively run on NeuronCores. You can use standard PyTorch custom operator programming interfaces to migrate CPU custom operators to Neuron and implement new experimental operators, all without any intimate knowledge of the NeuronCore hardware.
  • NeuronLink v2 – Inf2 instances are the first inference-optimized instance on Amazon EC2 to support distributed inference with direct ultra-high-speed connectivity—NeuronLink v2—between chips. NeuronLink v2 uses collective communications (CC) operators such as all-reduce to run high-performance inference pipelines across all chips.

The following Inf2 distributed inference benchmarks show throughput and cost improvements for OPT-30B and OPT-66B models over comparable inference-optimized Amazon EC2 instances.

Amazon EC2 Inf2 Benchmarks

Now, let me show you how to get started with Amazon EC2 Inf2 instances.

Get Started with Inf2 Instances
The AWS Neuron SDK integrates AWS Inferentia2 into popular machine learning (ML) frameworks like PyTorch. The Neuron SDK includes a compiler, runtime, and profiling tools and is constantly being updated with new features and performance optimizations.

In this example, I will compile and deploy a pre-trained BERT model from Hugging Face on an EC2 Inf2 instance using the available PyTorch Neuron packages. PyTorch Neuron is based on the PyTorch XLA software package and enables the conversion of PyTorch operations to AWS Inferentia2 instructions.

SSH into your Inf2 instance and activate a Python virtual environment that includes the PyTorch Neuron packages. If you’re using a Neuron-provided AMI, you can activate the preinstalled environment by running the following command:

source aws_neuron_venv_pytorch_p37/bin/activate

Now, with only a few changes to your code, you can compile your PyTorch model into an AWS Neuron-optimized TorchScript. Let’s start with importing torch, the PyTorch Neuron package torch_neuronx, and the Hugging Face transformers library.

import torch
import torch_neuronx from transformers import AutoTokenizer, AutoModelForSequenceClassification
import transformers
...

Next, let’s build the tokenizer and model.

name = "bert-base-cased-finetuned-mrpc"
tokenizer = AutoTokenizer.from_pretrained(name)
model = AutoModelForSequenceClassification.from_pretrained(name, torchscript=True)

We can test the model with example inputs. The model expects two sentences as input, and its output is whether or not those sentences are a paraphrase of each other.

def encode(tokenizer, *inputs, max_length=128, batch_size=1):
    tokens = tokenizer.encode_plus(
        *inputs,
        max_length=max_length,
        padding='max_length',
        truncation=True,
        return_tensors="pt"
    )
    return (
        torch.repeat_interleave(tokens['input_ids'], batch_size, 0),
        torch.repeat_interleave(tokens['attention_mask'], batch_size, 0),
        torch.repeat_interleave(tokens['token_type_ids'], batch_size, 0),
    )

# Example inputs
sequence_0 = "The company Hugging Face is based in New York City"
sequence_1 = "Apples are especially bad for your health"
sequence_2 = "Hugging Face's headquarters are situated in Manhattan"

paraphrase = encode(tokenizer, sequence_0, sequence_2)
not_paraphrase = encode(tokenizer, sequence_0, sequence_1)

# Run the original PyTorch model on examples
paraphrase_reference_logits = model(*paraphrase)[0]
not_paraphrase_reference_logits = model(*not_paraphrase)[0]

print('Paraphrase Reference Logits: ', paraphrase_reference_logits.detach().numpy())
print('Not-Paraphrase Reference Logits:', not_paraphrase_reference_logits.detach().numpy())

The output should look similar to this:

Paraphrase Reference Logits:     [[-0.34945598  1.9003887 ]]
Not-Paraphrase Reference Logits: [[ 0.5386365 -2.2197142]]

Now, the torch_neuronx.trace() method sends operations to the Neuron Compiler (neuron-cc) for compilation and embeds the compiled artifacts in a TorchScript graph. The method expects the model and a tuple of example inputs as arguments.

neuron_model = torch_neuronx.trace(model, paraphrase)

Let’s test the Neuron-compiled model with our example inputs:

paraphrase_neuron_logits = neuron_model(*paraphrase)[0]
not_paraphrase_neuron_logits = neuron_model(*not_paraphrase)[0]

print('Paraphrase Neuron Logits: ', paraphrase_neuron_logits.detach().numpy())
print('Not-Paraphrase Neuron Logits: ', not_paraphrase_neuron_logits.detach().numpy())

The output should look similar to this:

Paraphrase Neuron Logits: [[-0.34915772 1.8981738 ]]
Not-Paraphrase Neuron Logits: [[ 0.5374032 -2.2180378]]

That’s it. With just a few lines of code changes, we compiled and ran a PyTorch model on an Amazon EC2 Inf2 instance. To learn more about which DL model architectures are a good fit for AWS Inferentia2 and the current model support matrix, visit the AWS Neuron Documentation.

Available Now
You can launch Inf2 instances today in the AWS US East (Ohio) and US East (N. Virginia) Regions as On-Demand, Reserved, and Spot Instances or as part of a Savings Plan. As usual with Amazon EC2, you pay only for what you use. For more information, see Amazon EC2 pricing.

Inf2 instances can be deployed using AWS Deep Learning AMIs, and container images are available via managed services such as Amazon SageMaker, Amazon Elastic Kubernetes Service (Amazon EKS), Amazon Elastic Container Service (Amazon ECS), and AWS ParallelCluster.

To learn more, visit our Amazon EC2 Inf2 instances page, and please send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Antje