Tag Archives: launch

Amazon DataZone introduces OpenLineage-compatible data lineage visualization in preview

Post Syndicated from Leonardo Gomez original https://aws.amazon.com/blogs/big-data/amazon-datazone-introduces-openlineage-compatible-data-lineage-visualization-in-preview/

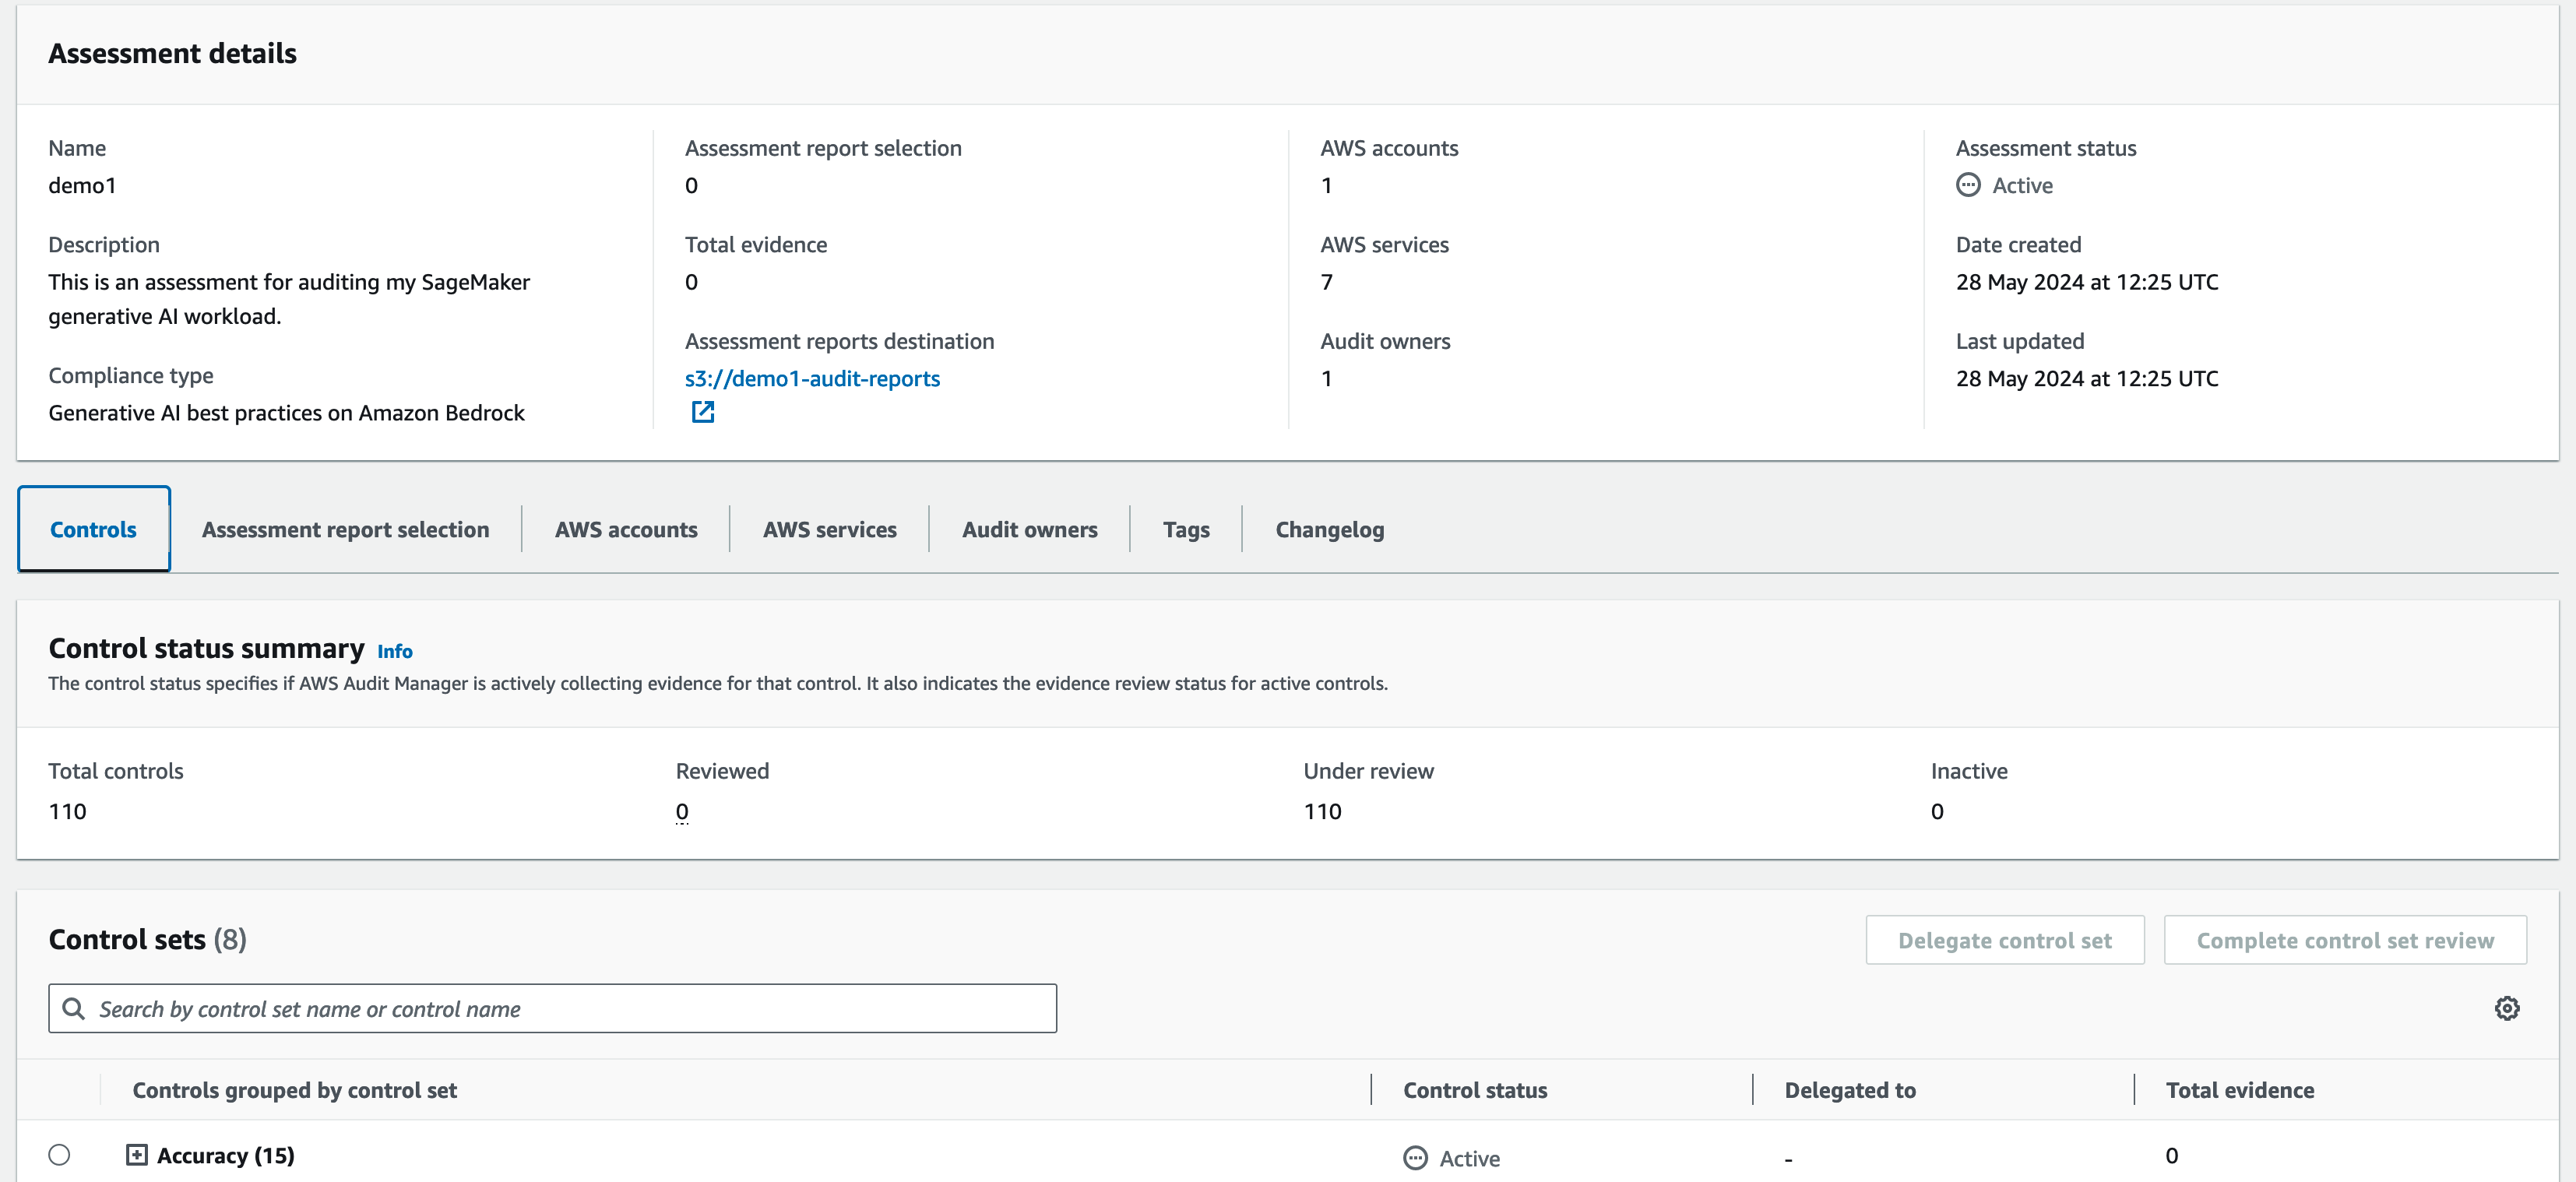
We are excited to announce the preview of API-driven, OpenLineage-compatible data lineage in Amazon DataZone to help you capture, store, and visualize lineage of data movement and transformations of data assets on Amazon DataZone.

With the Amazon DataZone OpenLineage-compatible API, domain administrators and data producers can capture and store lineage events beyond what is available in Amazon DataZone, including transformations in Amazon Simple Storage Service (Amazon S3), AWS Glue, and other AWS services. This provides a comprehensive view for data consumers browsing in Amazon DataZone, who can gain confidence of an asset’s origin, and data producers, who can assess the impact of changes to an asset by understanding its usage.

In this post, we discuss the latest features of data lineage in Amazon DataZone, its compatibility with OpenLineage, and how to get started capturing lineage from other services such as AWS Glue, Amazon Redshift, and Amazon Managed Workflows for Apache Airflow (Amazon MWAA) into Amazon DataZone through the API.

Why it matters to have data lineage

Data lineage gives you an overarching view into data assets, allowing you to see the origin of objects and their chain of connections. Data lineage enables tracking the movement of data over time, providing a clear understanding of where the data originated, how it has changed, and its ultimate destination within the data pipeline. With transparency around data origination, data consumers gain trust that the data is correct for their use case. Data lineage information is captured at levels such as tables, columns, and jobs, allowing you to conduct impact analysis and respond to data issues because, for example, you can see how one field impacts downstream sources. This equips you to make well-informed decisions before committing changes and avoid unwanted changes downstream.

Data lineage in Amazon DataZone is an API-driven, OpenLineage-compatible feature that helps you capture and visualize lineage events from OpenLineage-enabled systems or through an API, to trace data origins, track transformations, and view cross-organizational data consumption. The lineage visualized includes activities inside the Amazon DataZone business data catalog. Lineage captures the assets cataloged as well as the subscribers to those assets and to activities that happen outside the business data catalog captured programmatically using the API.

Additionally, Amazon DataZone versions lineage with each event, enabling you to visualize lineage at any point in time or compare transformations across an asset’s or job’s history. This historical lineage provides a deeper understanding of how data has evolved, which is essential for troubleshooting, auditing, and enforcing the integrity of data assets.

The following screenshot shows an example lineage graph visualized with the Amazon DataZone data catalog.

Introduction to OpenLineage compatible data lineage

The need to capture data lineage consistently across various analytical services and combine them into a unified object model is key in uncovering insights from the lineage artifact. OpenLineage is an open source project that offers a framework to collect and analyze lineage. It also offers reference implementation of an object model to persist metadata along with integration to major data and analytics tools.

The following are key concepts in OpenLineage:

  • Lineage events – OpenLineage captures lineage information through a series of events. An event is anything that represents a specific operation performed on the data that occurs in a data pipeline, such as data ingestion, transformation, or data consumption.
  • Lineage entities – Entities in OpenLineage represent the various data objects involved in the lineage process, such as datasets and tables.
  • Lineage runs – A lineage run represents a specific run of a data pipeline or a job, encompassing multiple lineage events and entities.
  • Lineage form types – Form types, or facets, provide additional metadata or context about lineage entities or events, enabling richer and more descriptive lineage information. OpenLineage offers facets for runs, jobs, and datasets, with the option to build custom facets.

The Amazon DataZone data lineage API is OpenLineage compatible and extends OpenLineage’s functionality by providing a materialization endpoint to persist the lineage outputs in an extensible object model. OpenLineage offers integrations for certain sources, and integration of these sources with Amazon DataZone is straightforward because the Amazon DataZone data lineage API understands the format and translates to the lineage data model.

The following diagram illustrates an example of the Amazon DataZone lineage data model.

In Amazon DataZone, every lineage node represents an underlying resource—there is a 1:1 mapping of the lineage node with a logical or physical resource such as table, view, or asset. The nodes represent a specific job with a specific run, or a node for a table or asset, and one node for a subscription target.

Each version of a node captures what happened to the underlying resource at that specific timestamp. In Amazon DataZone, lineage not only shares the story of data movement outside it, but it also represents the lineage of activities inside Amazon DataZone, such as asset creation, curation, publishing, and subscription.

To hydrate the lineage model in Amazon DataZone, two types of lineage are captured:

  • Lineage activities inside Amazon DataZone – This includes assets added to the catalog and published, and then details about the subscriptions are captured automatically. When you’re in the producer project context (for example, if the project you’re selected is the owning project of the asset you are browsing and you’re a member of that project), you will see two states of the dataset node:
    • The inventory asset type node defines the asset in the catalog that is in an unpublished stage. Other users can’t subscribe to the inventory asset. To learn more, refer to Creating inventory and published data in Amazon DataZone.
    • The published asset type represents the actual asset that is discoverable by data users across the organization. This is the asset type that can be subscribed by other project members. If you are a consumer and not part of the producing project of that asset, you will only see the published asset node.
  • Lineage activities outside of Amazon DataZone can be captured programmatically using the PostLineageEvent With these events captured either upstream or downstream of cataloged assets, data producers and consumers get a comprehensive view of data movement to check the origin of data or its consumption. We discuss how to use the API to capture lineage events later in this post.

There are two different types of lineage nodes available in Amazon DataZone:

  • Dataset node – In Amazon DataZone, lineage visualizes nodes that represent tables and views. Depending on the context of the project, the producers will be able to view both the inventory and published asset, whereas consumers can only view the published asset. When you first open the lineage tab on the asset details page, the cataloged dataset node will be the starting point for lineage graph traversal upstream or downstream. Dataset nodes include lineage nodes automated from Amazon DataZone and custom lineage nodes:
    • Automated dataset nodes – These nodes include information about AWS Glue or Amazon Redshift assets published in the Amazon DataZone catalog. They’re automatically generated and include a corresponding AWS Glue or Amazon Redshift icon within the node.
    • Custom dataset nodes – These nodes include information about assets that are not published in the Amazon DataZone catalog. They’re created manually by domain administrators (producers) and are represented by a default custom asset icon within the node. These are essentially custom lineage nodes created using the OpenLineage event format.
  • Job (run) node – This node captures the details of the job, which represents the latest run of a particular job and its run details. This node also captures multiple runs of the job and can be viewed on the History tab of the node details. Node details are made visible when you choose the icon.

Visualizing lineage in Amazon DataZone

Amazon DataZone offers a comprehensive experience for data producers and consumers. The asset details page provides a graphical representation of lineage, making it straightforward to visualize data relationships upstream or downstream. The asset details page provides the following capabilities to navigate the graph:

  • Column-level lineage – You can expand column-level lineage when available in dataset nodes. This automatically shows relationships with upstream or downstream dataset nodes if source column information is available.
  • Column search – If the dataset has more than 10 columns, the node presents pagination to navigate to columns not initially presented. To quickly view a particular column, you can search on the dataset node that lists just the searched column.
  • View dataset nodes only – If you want filter out the job nodes, you can choose the Open view control icon in the graph viewer and toggle the Display dataset nodes only This will remove all the job nodes from the graph and let you navigate just the dataset nodes.
  • Details pane – Each lineage node captures and displays the following details:
    • Every dataset node has three tabs: Lineage info, Schema, and History. The History tab lists the different versions of lineage event captured for that node.
    • The job node has a details pane to display job details with the tabs Job info and History. The details pane also captures queries or expressions run as part of the job.
  • Version tabs – All lineage nodes in Amazon DataZone data lineage will have versioning, captured as history, based on lineage events captured. You can view lineage at a selected timestamp that opens a new tab on the lineage page to help compare or contrast between the different timestamps.

The following screenshot shows an example of data lineage visualization.

You can experience the visualization with sample data by choosing Preview on the Lineage tab and choosing the Try sample lineage link. This opens a new browser tab with sample data to test and learn about the feature with or without a guided tour, as shown in the following screenshot.

Solution overview

Now that we understand the capabilities of the new data lineage feature in Amazon DataZone, let’s explore how you can get started in capturing lineage from AWS Glue tables and ETL (extract, transform, and load) jobs, Amazon Redshift, and Amazon MWAA.

The getting started scripts are also available in Amazon DataZone’s new GitHub repository.

Prerequisites

For this walkthrough, you should have the following prerequisites:

If the AWS account you use to follow this post uses AWS Lake Formation to manage permissions on the AWS Glue Data Catalog, make sure that you log in as a user with access to create databases and tables. For more information, refer to Implicit Lake Formation permissions.

Launch the CloudFormation stack

To create your resources for this use case using AWS CloudFormation, complete the following steps:

  1. Launch the CloudFormation stack in us-east-1:
  2. For Stack name, enter a name for your stack.
  3. Choose Next.
  4. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names.
  5. Choose Create stack.

Wait for the stack formation to finish provisioning the resources. When you see the CREATE_COMPLETE status, you can proceed to the next steps.

Capture lineage from AWS Glue tables

For this example, we use CloudShell, which is a browser-based shell, to run the commands necessary to harvest lineage metadata from AWS Glue tables. Complete the following steps:

  1. On the AWS Glue console, choose Crawlers in the navigation pane.
  2. Select the AWSomeRetailCrawler crawler created by the CloudFormation template.
  3. Choose Run.

When the crawler is complete, you’ll see a Succeeded status.

Now let’s harvest the lineage metadata using CloudShell.

  1. Download the extract_glue_crawler_lineage.py file.
  2. On the Amazon DataZone console, open CloudShell.
  1. On the Actions menu, choose Update file.
  2. Upload the extract_glue_crawler_lineage.py file.

  3. Run the following commands:
    sudo yum -y install python3
    python3 -m venv env
    . env/bin/activate
    pip install boto3

You should get the following results.

  1. After all the libraries and dependencies are configured, run the following command to harvest the lineage metadata from the inventory table:
    python extract_glue_crawler_lineage.py -d awsome_retail_db -t inventory -r us-east-1 -i dzd_Your_doamin

  2. The script asks for verification of the settings provided; enter Yes.

You should receive a notification indicating that the script ran successfully.

After you capture the lineage information from the Inventory table, complete the following steps to run the data source.

  1. On the Amazon DataZone data portal, open the Sales
  2. On the Data tab, choose Data sources in the navigation pane.
  1. Select your data source job and choose Run.

For this example, we had a data source job called SalesDLDataSourceV2 already created pointing to the awesome_retail_db database. To learn more about how to create data source jobs, refer to Create and run an Amazon DataZone data source for the AWS Glue Data Catalog.

After the job runs successfully, you should see a confirmation message.

Now let’s view the lineage diagram generated by Amazon DataZone.

  1. On the Data inventory tab, choose the Inventory table.
  2. On the Inventory asset page, choose the new Lineage tab.

On the Lineage tab, you can see that Amazon DataZone created three nodes:

  • Job / Job run – This is based on the AWS Glue crawler used to harvest the asset technical metadata
  • Dataset – This is based on the S3 object that contains the data related to this asset
  • Table – This is the AWS Glue table created by the crawler

If you choose the Dataset node, Amazon DataZone offers information about the S3 object used to create the asset.

Capture data lineage for AWS Glue ETL jobs

In the previous section, we covered how to generate a data lineage diagram on top of a data asset. Now let’s see how we can create one for an AWS Glue job.

The CloudFormation template that we launched earlier created an AWS Glue job called Inventory_Insights. This job gets data from the Inventory table and creates a new table called Inventory_Insights with the aggregated data of the total products available in all the stores.

The CloudFormation template also copied the openlineage-spark_2.12-1.9.1.jar file to the S3 bucket created for this post. This file is necessary to generate lineage metadata from the AWS Glue job. We use version 1.9.1, which is compatible with AWS Glue 3.0, the version used to create the AWS Glue job for this post. If you’re using a different version of AWS Glue, you need to download the corresponding OpenLineage Spark plugin file that matches your AWS Glue version.

The OpenLineage Spark plugin is not able to extract data lineage from AWS Glue Spark jobs that use AWS Glue DynamicFrames. Use Spark SQL DataFrames instead.

  1. Download the extract_glue_spark_lineage.py file.
  2. On the Amazon DataZone console, open CloudShell.
  3. On the Actions menu, choose Update file.
  4. Upload the extract_glue_spark_lineage.py file.
  5. On the CloudShell console, run the following command (if your CloudShell session expired, you can open a new session):
    python extract_glue_spark_lineage.py —region "us-east-1" —domain-identifier 'dzd_Your Domain'

  6. Confirm the information showed by the script by entering yes.

You will see the following message; this means that the script is ready to get the AWS Glue job lineage metadata after you run it.

Now let’s run the AWS Glue job created by the Cloud formation template.

  1. On the AWS Glue console, choose ETL jobs in the navigation pane.
  2. Select the Inventory_Insights job and choose Run job.

On the Job details tab, you will notice that the job has the following configuration:

  • Key --conf with value extraListeners=io.openlineage.spark.agent.OpenLineageSparkListener --conf spark.openlineage.transport.type=console --conf spark.openlineage.facets.custom_environment_variables=[AWS_DEFAULT_REGION;GLUE_VERSION;GLUE_COMMAND_CRITERIA;GLUE_PYTHON_VERSION;]
  • Key --user-jars-first with value true
  • Dependent JARs path set as the S3 path s3://{your bucket}/lib/openlineage-spark_2.12-1.9.1.jar
  • The AWS Glue version set as 3.0

During the run of the job, you will see the following output on the CloudShell console.

This means that the script has successfully harvested the lineage metadata from the AWS Glue job.

Now let’s create an AWS Glue table based on the data created by the AWS Glue job. For this example, we use an AWS Glue crawler.

  1. On the AWS Glue console, choose Crawlers in the navigation pane.
  2. Select the AWSomeRetailCrawler crawler created by the CloudFormation template and choose Run.

When the crawler is complete, you will see the following message.

Now let’s open the Amazon DataZone portal to see how the diagram is represented in Amazon DataZone.

  1. On the Amazon DataZone portal, choose the Sales project.
  2. On the Data tab, choose Inventory data in the navigation pane.
  3. Choose the inventory insights asset

On the Lineage tab, you can see the diagram created by Amazon DataZone. It shows three nodes:

    • The AWS Glue crawler used to create the AWS Glue table
    • The AWS Glue table created by the crawler
    • The Amazon DataZone cataloged asset
  1. To see the lineage information about the AWS Glue job that you ran to create the inventory_insights table, choose the arrows icon on the left side of the diagram.

Now you can see the full lineage diagram for the Inventory_insights table.

  1. Choose the blue arrow icon in the inventory node to the left of the diagram.

You can see the evolution of the columns and the transformations that they had.

When you choose any of the nodes that are part of the diagram, you can see more details. For example, the inventory_insights node shows the following information.

Capture lineage from Amazon Redshift

Let’s explore how to generate a lineage diagram from Amazon Redshift. In this example, we use AWS Cloud9 because it allows us to configure the connection to the virtual private cloud (VPC) where our Redshift cluster resides. For more information about AWS Cloud9, refer to the AWS Cloud9 User Guide.

The CloudFormation template included as part of this post doesn’t cover the creation of a Redshift cluster or the creation of the tables used in this section. To learn more about how to create a Redshift cluster, see Step 1: Create a sample Amazon Redshift cluster. We use the following query to create the tables needed for this section of the post:

Create SCHEMA market

create table market.retail_sales (
  id BIGINT primary key,
  name character varying not null
);

create table market.online_sales (
  id BIGINT primary key,
  name character varying not null
);

/* Important to insert some data in the table */
INSERT INTO market.retail_sales
VALUES (123, 'item1')

INSERT INTO market.online_sales
VALUES (234, 'item2')

create table market.sales AS
Select id, name from market.retail_sales
Union ALL
Select id, name from market.online_sales;

Remember to add the IP address of your AWS Cloud9 environment to the security group with access to the Redshift cluster.

  1. Download the requirements.txt and extract_redshift_lineage.py files.
  2. On the File menu, choose Upload Local Files.
  3. Upload the requirements.txt and extract_redshift_lineage.py files.
  4. Run the following commands:
    # Install Python 
    sudo yum -y install python3
    
    # dependency set up 
    python3 -m venv env 
    . env/bin/activate
    
    pip install -r requirements.txt

You should be able to see the following messages.

  1. To set the AWS credentials, run the following command:
    export AWS_ACCESS_KEY_ID=<<Your Access Key>>
    export AWS_SECRET_ACCESS_KEY=<<Your Secret Access Key>>
    export AWS_SESSION_TOKEN=<<Your Session Token>>

  2. Run the extract_redshift_lineage.py script to harvest the metadata necessary to generate the lineage diagram:
    python extract_redshift_lineage.py \
     -r region \
     -i dzd_your_dz_domain_id \
     -n your-redshift-cluster-endpoint \
     -t your-rs-port \
     -d your-database \
     -s the-starting-date

  3. Next, you will be prompted to enter the user name and password for the connection to your Amazon DataZone database.
  4. When you receive a confirmation message, enter yes.

If the configuration was done correctly, you will see the following confirmation message.

Now let’s see how the diagram was created in Amazon DataZone.

  1. On the Amazon DataZone data portal, open the Sales project.
  2. On the Data tab, choose Data sources.
  3. Run the data source job.

For this post, we already created a data source job called Sales_DW_Enviroment-default-datasource to add the Redshift data source to our Amazon DataZone project. To learn how to create a data source job, refer to Create and run an Amazon DataZone data source for Amazon Redshift

After you run the job, you’ll see the following confirmation message.

  1. On the Data tab, choose Inventory data in the navigation pane.
  2. Choose the total_sales asset.
  1. Choose the Lineage tab.

Amazon DataZone create a three-node lineage diagram for the total sales table; you can choose any node to view its details.

  1. Choose the arrows icon next to the Job/ Job run node to view a more complete lineage diagram.
  1. Choose the Job / Job run

The Job Info section shows the query that was used to create the total sales table.

Capture lineage from Amazon MWAA

Apache Airflow is an open-source platform for developing, scheduling, and monitoring batch-oriented workflows. Amazon MWAA is a managed service for Airflow that lets you use your current Airflow platform to orchestrate your workflows. OpenLineage supports integration with Airflow 2.6.3 using the openlineage-airflow package, and the same can be enabled on Amazon MWAA as a plugin. Once enabled, the plugin converts Airflow metadata to OpenLineage events, which are consumable by DataZone.PostLineageEvent.

The following diagram shows the setup required in Amazon MWAA to capture data lineage using OpenLineage and publish it to Amazon DataZone.

The workflow uses an Amazon MWAA DAG to invoke a data pipeline. The process is as follows:

  1. The openlineage-airflow plugin is configured on Amazon MWAA as a lineage backend. Metadata about the DAG run is passed to the plugin, which converts it into OpenLineage format.
  2. The lineage information collected is written to Amazon CloudWatch log group according to the Amazon MWAA environment.
  3. A helper function captures the lineage information from the log file and publishes it to Amazon DataZone using the PostLineageEvent API.

The example used in the post uses Amazon MWAA version 2.6.3 and OpenLineage plugin version 1.4.1. For other Airflow versions supported by OpenLineage, refer to Supported Airflow versions.

Configure the OpenLineage plugin on Amazon MWAA to capture lineage

When harvesting lineage using OpenLineage, a Transport configuration needs to be set up, which tells OpenLineage where to emit the events to, for example the console or an HTTP endpoint. You can use ConsoleTransport, which logs the OpenLineage events in the Amazon MWAA task CloudWatch log group, which can then be published to Amazon DataZone using a helper function.

Specify the following in the requirements.txt file added to the S3 bucket configured for Amazon MWAA:

openlineage-airflow==1.4.1

In the Airflow logging configuration section under the MWAA configuration for the Airflow environment, enable Airflow task logs with log level INFO. The following screenshot shows a sample configuration.

A successful configuration will add a plugin to Airflow, which can be verified from the Airflow UI by choosing Plugins on the Admin menu.

In this post, we use a sample DAG to hydrate data to Redshift tables. The following screenshot shows the DAG in graph view.

Run the DAG and upon successful completion of a run, open the Amazon MWAA task CloudWatch log group for your Airflow environment (airflow-env_name-task) and filter based on the expression console.py to select events emitted by OpenLineage. The following screenshot shows the results.

Publish lineage to Amazon DataZone

Now that you have the lineage events emitted to CloudWatch, the next step is to publish them to Amazon DataZone to associate them to a data asset and visualize them on the business data catalog.

  1. Download the files requirements.txt and airflow_cw_parse_log.py and gather environment details like AWS region, Amazon MWAA environment name and Amazon DataZone Domain ID.
  2. The Amazon MWAA environment name can be obtained from the Amazon MWAA console.
  3. The Amazon DataZone domain ID can be obtained from Amazon DataZone service console or from the Amazon DataZone portal.
  4. Navigate to CloudShell and choose Upload files on the Actions menu to upload the files requirements.txt and extract_airflow_lineage.py.

  5. After the files are uploaded, run the following script to filter lineage events from the Airflow task logs and publish them to Amazon DataZone:
    # Set up virtual env and install dependencies
    python -m venv env
    pip install -r requirements.txt
    . env/bin/activate
    
    # run the script
    python extract_airflow_lineage.py \
      --region us-east-1 \
      --domain-identifier your_domain_identifier \
      --airflow-environment-name your_airflow_environment_name

The function extract_airflow_lineage.py filters the lineage events from the Amazon MWAA task log group and publishes the lineage to the specified domain within Amazon DataZone.

Visualize lineage on Amazon DataZone

After the lineage is published to DataZone, open your DataZone project, navigate to the Data tab and chose a data asset that was accessed by the Amazon MWAA DAG. In this case, it is a subscribed asset.

Navigate to the Lineage tab to visualize the lineage published to Amazon DataZone.

Choose a node to look at additional lineage metadata. In the following screenshot, we can observe the producer of the lineage has been marked as airflow.

Conclusion

In this post, we shared the preview feature of data lineage in Amazon DataZone, how it works, and how you can capture lineage events, from AWS Glue, Amazon Redshift, and Amazon MWAA, to be visualized as part of the asset browsing experience.

To learn more about Amazon DataZone and how to get started, refer to the Getting started guide. Check out the YouTube playlist for some of the latest demos of Amazon DataZone and short descriptions of the capabilities available.


About the Authors
Leonardo Gomez is a Principal Analytics Specialist at AWS, with over a decade of experience in data management. Specializing in data governance, he assists customers worldwide in maximizing their data’s potential while promoting data democratization. Connect with him on LinkedIn.

Priya Tiruthani is a Senior Technical Product Manager with Amazon DataZone at AWS. She focuses on improving data discovery and curation required for data analytics. She is passionate about building innovative products to simplify customers’ end-to-end data journey, especially around data governance and analytics. Outside of work, she enjoys being outdoors to hike, capture nature’s beauty, and recently play pickleball.

Ron Kyker is a Principal Engineer with Amazon DataZone at AWS, where he helps drive innovation, solve complex problems, and set the bar for engineering excellence for his team. Outside of work, he enjoys board gaming with friends and family, movies, and wine tasting.

Srinivasan Kuppusamy is a Senior Cloud Architect – Data at AWS ProServe, where he helps customers solve their business problems using the power of AWS Cloud technology. His areas of interests are data and analytics, data governance, and AI/ML.

AWS Weekly Roundup: Amazon S3 Access Grants, AWS Lambda, European Sovereign Cloud Region, and more (July 8, 2024).

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-s3-access-grants-aws-lambda-european-sovereign-cloud-region-and-more-july-8-2024/

I counted only 21 AWS news since last Monday, most of them being Regional expansions of existing services and capabilities. I hope you enjoyed a relatively quiet week, because this one will be busier.

This week, we’re welcoming our customers and partners at the Jacob Javits Convention Center for the AWS Summit New York on Wednesday, July 10. I can tell you there is a stream of announcements coming, if I judge by the number of AWS News Blog posts ready to be published.

I am writing these lines just before packing my bag to attend the AWS Community Day in Douala, Cameroon next Saturday. I can’t wait to meet our customers and partners, students, and the whole AWS community there.

But for now, let’s look at last week’s new announcements.

Last week’s launches
Here are the launches that got my attention.

Amazon Simple Storage Service (Amazon S3) Access Grants now integrate with Amazon SageMaker and open souce Python frameworks – Amazon S3 Access Grants maps identities in directories such as Active Directory or AWS Identity and Access Management (IAM) principals, to datasets in S3. The integration with Amazon SageMaker Studio for machine learning (ML) helps you map identities to your machine learning (ML) datasets in S3. The integration with the AWS SDK for Python (Boto3) plugin replaces any custom code required to manage data permissions, so you can use S3 Access Grants in open source Python frameworks such as Django, TensorFlow, NumPy, Pandas, and more.

AWS Lambda introduces new controls to make it easier to search, filter, and aggregate Lambda function logs – You can now capture your Lambda logs in JSON structured format without bringing your own logging libraries. You can also control the log level (for example, ERROR, DEBUG, or INFO) of your Lambda logs without making any code changes. Lastly, you can choose the Amazon CloudWatch log group to which Lambda sends your logs.

Amazon DataZone introduces fine-grained access control – Amazon DataZone has introduced fine-grained access control, providing data owners granular control over their data at row and column levels. You use Amazon DataZone to catalog, discover, analyze, share, and govern data at scale across organizational boundaries with governance and access controls. Data owners can now restrict access to specific records of data instead of granting access to an entire dataset.

AWS Direct Connect proposes native 400 Gbps dedicated connections at select locations – AWS Direct Connect provides private, high-bandwidth connectivity between AWS and your data center, office, or colocation facility. Native 400 Gbps connections provide higher bandwidth without the operational overhead of managing multiple 100 Gbps connections in a link aggregation group. The increased capacity delivered by 400 Gbps connections is particularly beneficial to applications that transfer large-scale datasets, such as for ML and large language model (LLM) training or advanced driver assistance systems for autonomous vehicles.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS news
Here are some additional news items that you might find interesting:

The list of services available at launch in the upcoming AWS Europe Sovereign Cloud Region is available – we shared the list of AWS services that will be initially available at launch in the new AWS European Sovereign Cloud Region. The list has no surprises. Services for security, networking, storage, computing, containers, artificial intelligence (AI), and serverless will be available at launch. We are building the AWS European Sovereign Cloud to offer public sector organizations and customers in highly regulated industries further choice to help them meet their unique digital sovereignty requirements, as well as stringent data residency, operational autonomy, and resiliency requirements. This is an investment of 7.8 billion euros (approximately $8.46 billion). The new Region will be available by the end of 2025.

Upcoming AWS events
Check your calendars and sign up for upcoming AWS events:

AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. To learn more about future AWS Summit events, visit the AWS Summit page. Register in your nearest city: New York (July 10), Bogotá (July 18), and Taipei (July 23–24).

AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world. Upcoming AWS Community Days are in Cameroon (July 13), Aotearoa (August 15), and Nigeria (August 24).

Browse all upcoming AWS led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— seb

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Enhance data security with fine-grained access controls in Amazon DataZone

Post Syndicated from Deepmala Agarwal original https://aws.amazon.com/blogs/big-data/enhance-data-security-with-fine-grained-access-controls-in-amazon-datazone/

Fine-grained access control is a crucial aspect of data security for modern data lakes and data warehouses. As organizations handle vast amounts of data across multiple data sources, the need to manage sensitive information has become increasingly important. Making sure the right people have access to the right data, without exposing sensitive information to unauthorized individuals, is essential for maintaining data privacy, compliance, and security.

Today, Amazon DataZone has introduced fine-grained access control, providing you granular control over your data assets in the Amazon DataZone business data catalog across data lakes and data warehouses. With the new capability, data owners can now restrict access to specific records of data at row and column levels, instead of granting access to the entire data asset. For example, if your data contains columns with sensitive information such as personally identifiable information (PII), you can restrict access to only the necessary columns, making sure sensitive information is protected while still allowing access to non-sensitive data. Similarly, you can control access at the row level, allowing users to see only the records that are relevant to their role or task.

In this post, we discuss how to implement fine-grained access control with row and column asset filters using this new feature in Amazon DataZone.

Row and column filters

Row filters enable you to restrict access to specific rows based on criteria you define. For instance, if your table contains data for two regions (America and Europe) and you want to make sure that employees in Europe only access data relevant to their region, you can create a row filter that excludes rows where the region is not Europe (for example, region != 'Europe'). This way, employees in America won’t have access to Europe’s data.

Column filters allow you to limit access to specific columns within your data assets. For example, if your table includes sensitive information such as PII, you can create a column filter to exclude PII columns. This makes sure subscribers can only access non-sensitive data.

The row and column asset filters in Amazon DataZone enable you to control who can access what using a consistent, business user-friendly mechanism for all of your data across AWS data lakes and data warehouses. To use fine-grained access control in Amazon DataZone, you can create row and column filters on top of your data assets in the Amazon DataZone business data catalog. When a user requests a subscription to your data asset, you can approve the subscription by applying the appropriate row and column filters. Amazon DataZone enforces these filters using AWS Lake Formation and Amazon Redshift, making sure the subscriber can only access the rows and columns that they are authorized to use.

Solution overview

To demonstrate the new capability, we consider a sample customer use case where an electronics ecommerce platform is looking to implement fine-grained access controls using Amazon DataZone. The customer has multiple product categories, each operated by different divisions of the company. The platform governance team wants to make sure each division has visibility only to data belonging to their own categories. Additionally, the platform governance team needs to adhere to the finance team requirements that pricing information should be visible only to the finance team.

The sales team, acting as the data producer, has published an AWS Glue table called Product sales that contains data for both Laptops and Servers categories to the Amazon DataZone business data catalog using the project Product-Sales. The analytic teams in both the laptop and server divisions need to access this data for their respective analytics projects. The data owner’s objective is to grant data access to consumers based on the division they belong to. This means giving access to only rows of data with laptop sales to the laptops sales analytics team, and rows with servers sales to the server sales analytics team. Additionally, the data owner wants to restrict both teams from accessing the pricing data. This post demonstrates the implementation steps to achieve this use case in Amazon DataZone.

The steps to configure this solution are as follows:

  1. The publisher creates asset filters for limiting access:
    1. We create two row filters: a Laptop Only row filter that limits access to only the rows of data with laptop sales, and a Server Only row filter that limits access to the rows of data with server sales.
    2. We also create a column filter called exclude-price-columns that excludes the price-related columns from the Product Sales
  2. Consumers discover and request subscriptions:
    1. The analyst from the laptops division requests a subscription to the Product Sales data asset.
    2. The analyst from the servers division also request a subscription to the Product Sales data asset.
    3. Both subscription requests are sent to the publisher for approval.
  3. The publisher approves the subscriptions and applies the appropriate filters:
    1. The publisher approves the request from the analysts in the laptops division, applying the Laptop Only row filter and the exclude-price-columns columns filter.
    2. The publisher approves the request from the consumer in the servers division, applying the Server Only row filter and the exclude-price-columns columns filter.
  4. Consumers access the authorized data in Amazon Athena:
    1. After the subscription is approved, we query the data in Athena to make sure that the analyst from the laptops division can now access only the product sales data for the Laptop
    2. Similarly, the analyst from the servers division can access only the product sales data for the Server
    3. Both consumers can see all columns except the price-related columns, as per the applied column filter.

The following diagram illustrates the solution architecture and process flow.

Prerequisites

To follow along with this post, the publisher of the product sales data asset must have published a sales dataset in Amazon DataZone.

Publisher creates asset filters for limiting access

In this section, we detail the steps the publisher takes to create asset filers.

Create row filters

This dataset contains the product categories Laptops and Servers. We want to restrict access to the dataset that is authorized based on the product category. We use the row filter feature in Amazon DataZone to achieve this.

Amazon DataZone allows you to create row filters that can be used when approving subscriptions to make sure that the subscriber can only access rows of data as defined in the row filters. To create a row filter, complete the following steps:

  1. On the Amazon DataZone console, navigate to the product-sales project (the project to which the asset belongs).
  2. Navigate to the Data tab for the project.
  3. Choose Inventory data in the navigation pane, then the asset Product Sales, where you want to create the row filter.

You can add row filters for assets of type AWS Glue tables or Redshift tables.

  1. On the asset detail page, on the Asset filters tab, choose Add asset filter.

We create two row filters, one each for the Laptops and Servers categories.

  1. Complete the following steps to create a laptop only asset row filter:
    1. Enter a name for this filter (Laptop Only).
    2. Enter a description of the filter (Allow rows with product category as Laptop Only).
    3. For the filter type, select Row filter.
    4. For the row filter expression, enter one or more expressions:
      1. Choose the column Product Category from the column dropdown menu.
      2. Choose the operator = from the operator dropdown menu.
      3. Enter the value Laptops in the Value field.
    5. If you need to add another condition to the filter expression, choose Add condition. For this post, we create a filter with one condition.
    6. When using multiple conditions in the row filter expression, choose And or Or to link the conditions.
    7. You can also define the subscriber visibility. For this post, we kept the default value (No, show values to subscriber).
    8. Choose Create asset filter.
  2. Repeat the same steps to create a row filter called Server Only, except this time enter the value Servers in the Value field.

Create column filters

Next, we create column filters to restrict access to columns with price-related data. Complete the following steps:

  1. In the same asset, add another asset filter of type column filter.
  2. On the Asset filters tab, choose Add asset filter.
  3. For Name, enter a name for the filter (for this post, exclude-price-columns).
  4. For Description, enter a description of the filters (for this post, exclude price data columns).
  5. For the filter type, select Column to create the column filter. This will display all the available columns in the data asset’s schema.
  6. Select all columns except the price-related ones.
  7. Choose Create asset filter.

Consumers discover and request subscriptions

In this section, we switch to the role of an analyst from the laptop division who is working within the project Sales Analytics - Laptop. As the data consumer, we search the catalog to find the Product Sales data asset and request access by subscribing to it.

  1. Log in to your project as a consumer and search for the Product Sales data asset.
  2. On the Product Sales data asset details page, choose Subscribe.
  3. For Project, choose Sales Analytics – Laptops.
  4. For Reason for request, enter the reason for the subscription request.
  5. Choose Subscribe to submit the subscription request.

Publisher approves subscriptions with filters

After the subscription request is submitted, the publisher will receive the request, and they can approve it by following these steps:

  1. As the publisher, open the project Product-Sales.
  2. On the Data tab, choose Incoming requests in the left navigation pane.
  3. Locate the request and choose View request. You can filter by Pending to see only requests that are still open.

This opens the details of the request, where you can see details like who requested the access, for what project, and the reason for the request.

  1. To approve the request, there are two options:
    1. Full access – If you choose to approve the subscription with full access option, the subscriber will get access to all the rows and columns in our data asset.
    2. Approve with row and column filters – To limit access to specific rows and columns of data, you can choose the option to approve with row and column filters. For this post, we use both filters that we created earlier.
  2. Select Choose filter, then on the dropdown menu, choose the Laptops Only and pii-col-filter
  3. Choose Approve to approve the request.

After access is granted and fulfilled, the subscription looks as shown in the following screenshot.

  1. Now let’s log in as a consumer from the server division.
  2. Repeat the same steps, but this time, while approving the subscription, the publisher of sales data approves with the Server only The other steps remain the same.

Consumers access authorized data in Athena

Now that we have successfully published an asset to the Amazon DataZone catalog and subscribed to it, we can analyze it. Let’s log in as a consumer from the laptop division.

  1. In the Amazon DataZone data portal, choose the consumer project Sales Analytics - Laptops.
  2. On the Schema tab, we can view the subscribed assets.
  3. Choose the project Sales Analytics - Laptops and choose the Overview
  4. In the right pane, open the Athena environment.

We can now run queries on the subscribed table.

  1. Choose the table under Tables and views, then choose Preview to view the SELECT statement in the query editor.
  2. Run a query as the consumer of Sales Analytics - Laptops, in which we can view data only with product category Laptops.

Under Tables and views, you can expand the table product_sales. The price-related columns are not visible in the Athena environment for querying.

  1. Next, you can switch to the role of analyst from the server division and analyze the dataset in similar way.
  2. We run the same query and see that under product_category, the analyst can see Servers only.

Conclusion

Amazon DataZone offers a straightforward way to implement fine-grained access controls on top of your data assets. This feature allows you to define column-level and row-level filters to enforce data privacy before the data is available to data consumers. Amazon DataZone fine-grained access control is generally available in all AWS Regions that support Amazon DataZone.

Try out the fine-grained access control feature in your own use case, and let us know your feedback in the comments section.


About the Authors

Deepmala Agarwal works as an AWS Data Specialist Solutions Architect. She is passionate about helping customers build out scalable, distributed, and data-driven solutions on AWS. When not at work, Deepmala likes spending time with family, walking, listening to music, watching movies, and cooking!

Leonardo Gomez is a Principal Analytics Specialist Solutions Architect at AWS. He has over a decade of experience in data management, helping customers around the globe address their business and technical needs. Connect with him on LinkedIn.

Utkarsh Mittal is a Senior Technical Product Manager for Amazon DataZone at AWS. He is passionate about building innovative products that simplify customers’ end-to-end analytics journeys. Outside of the tech world, Utkarsh loves to play music, with drums being his latest endeavor.
AWS Weekly Roundup: AI21 Labs’ Jamba-Instruct in Amazon Bedrock, Amazon WorkSpaces Pools, and more (July 1, 2024)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-ai21-labs-jamba-instruct-in-amazon-bedrock-amazon-workspaces-pools-and-more-july-1-2024/

AWS Summit New York is 10 days away, and I am very excited about the new announcements and more than 170 sessions. There will be A Night Out with AWS event after the summit for professionals from the media and entertainment, gaming, and sports industries who are existing Amazon Web Services (AWS) customers or have a keen interest in using AWS Cloud services for their business. You’ll have the opportunity to relax, collaborate, and build new connections with AWS leaders and industry peers.

Let’s look at the last week’s new announcements.

Last week’s launches
Here are the launches that got my attention.

AI21 Labs’ Jamba-Instruct now available in Amazon Bedrock – AI21 Labs’ Jamba-Instruct is an instruction-following large language model (LLM) for reliable commercial use, with the ability to understand context and subtext, complete tasks from natural language instructions, and ingest information from long documents or financial filings. With strong reasoning capabilities, Jamba-Instruct can break down complex problems, gather relevant information, and provide structured outputs to enable uses like Q&A on calls, summarizing documents, building chatbots, and more. For more information, visit AI21 Labs in Amazon Bedrock and the Amazon Bedrock User Guide.

Amazon WorkSpaces Pools, a new feature of Amazon WorkSpaces – You can now create a pool of non-persistent virtual desktops using Amazon WorkSpaces and save costs by sharing them across users who receive a fresh desktop each time they sign in. WorkSpaces Pools provides the flexibility to support shared environments like training labs and contact centers, and some user settings like bookmarks and files stored in a central storage repository such as Amazon Simple Storage Service (Amazon S3) or Amazon FSx can be saved for improved personalization. You can use AWS Auto Scaling to automatically scale the pool of virtual desktops based on usage metrics or schedules. For pricing information, refer to the Amazon WorkSpaces Pricing page.

API-driven, OpenLineage-compatible data lineage visualization in Amazon DataZone (preview) – Amazon DataZone introduces a new data lineage feature that allows you to visualize how data moves from source to consumption across organizations. The service captures lineage events from OpenLineage-enabled systems or through API to trace data transformations. Data consumers can gain confidence in an asset’s origin, and producers can assess the impact of changes by understanding its consumption through the comprehensive lineage view. Additionally, Amazon DataZone versions lineage with each event to enable visualizing lineage at any point in time or comparing transformations across an asset or job’s history. To learn more, visit Amazon DataZone, read my News Blog post, and get started with data lineage documentation.

Knowledge Bases for Amazon Bedrock now offers observability logs – You can now monitor knowledge ingestion logs through Amazon CloudWatch, S3 buckets, or Amazon Data Firehose streams. This provides enhanced visibility into whether documents were successfully processed or encountered failures during ingestion. Having these comprehensive insights promptly ensures that you can efficiently determine when your documents are ready for use. For more details on these new capabilities, refer to the Knowledge Bases for Amazon Bedrock documentation.

Updates and expansion to the AWS Well-Architected Framework and Lens Catalog – We announced updates to the AWS Well-Architected Framework and Lens Catalog to provide expanded guidance and recommendations on architectural best practices for building secure and resilient cloud workloads. The updates reduce redundancies and enhance consistency in resources and framework structure. The Lens Catalog now includes the new Financial Services Industry Lens and updates to the Mergers and Acquisitions Lens. We also made important updates to the Change Enablement in the Cloud whitepaper. You can use the updated Well-Architected Framework and Lens Catalog to design cloud architectures optimized for your unique requirements by following current best practices.

Cross-account machine learning (ML) model sharing support in Amazon SageMaker Model Registry – Amazon SageMaker Model Registry now integrates with AWS Resource Access Manager (AWS RAM), allowing you to easily share ML models across AWS accounts. This helps data scientists, ML engineers, and governance officers access models in different accounts like development, staging, and production. You can share models in Amazon SageMaker Model Registry by specifying the model in the AWS RAM console and granting access to other accounts. This new feature is now available in all AWS Regions where SageMaker Model Registry is available except GovCloud Regions. To learn more, visit the Amazon SageMaker Developer Guide.

AWS CodeBuild supports Arm-based workloads using AWS Graviton3 – AWS CodeBuild now supports natively building and testing Arm workloads on AWS Graviton3 processors without additional configuration, providing up to 25% higher performance and 60% lower energy usage than previous Graviton processors. To learn more about CodeBuild’s support for Arm, visit our AWS CodeBuild User Guide.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

We launched existing services and instance types in additional Regions:

Other AWS news
Here are some additional news items that you might find interesting:

Top reasons to build and scale generative AI applications on Amazon Bedrock – Check out Jeff Barr’s video, where he discusses why our customers are choosing Amazon Bedrock to build and scale generative artificial intelligence (generative AI) applications that deliver fast value and business growth. Amazon Bedrock is becoming a preferred platform for building and scaling generative AI due to its features, innovation, availability, and security. Leading organizations across diverse sectors use Amazon Bedrock to speed their generative AI work, like creating intelligent virtual assistants, creative design solutions, document processing systems, and a lot more.

Four ways AWS is engineering infrastructure to power generative AI – We continue to optimize our infrastructure to support generative AI at scale through innovations like delivering low-latency, large-scale networking to enable faster model training, continuously improving data center energy efficiency, prioritizing security throughout our infrastructure design, and developing custom AI chips like AWS Trainium to increase computing performance while lowering costs and energy usage. Read the new blog post about how AWS is engineering infrastructure for generative AI.

AWS re:Inforce 2024 re:Cap – It’s been 2 weeks since AWS re:Inforce 2024, our annual cloud-security learning event. Check out the summary of the event prepared by Wojtek.

Upcoming AWS events
Check your calendars and sign up for upcoming AWS events:

AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. To learn more about future AWS Summit events, visit the AWS Summit page. Register in your nearest city: New York (July 10), Bogotá (July 18), and Taipei (July 23–24).

AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world. Upcoming AWS Community Days are in Cameroon (July 13), Aotearoa (August 15), and Nigeria (August 24).

Browse all upcoming AWS led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Esra

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Amazon WorkSpaces Pools: Cost-effective, non-persistent virtual desktops

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/amazon-workspaces-pools-cost-effective-non-persistent-virtual-desktops/

You can now create a pool of non-persistent virtual desktops using Amazon WorkSpaces and share them across a group of users. As the desktop administrator you can manage your entire portfolio of persistent and non-persistent virtual desktops using one GUI, command line, or set of API-powered tools. Your users can log in to these desktops using a browser, a client application (Windows, Mac, or Linux), or a thin client device.

Amazon WorkSpaces Pools (non-persistent desktops)
WorkSpaces Pools ensures that each user gets the same applications and the same experience. When the user logs in, they always get access to a fresh WorkSpace that’s based on the latest configuration for the pool, centrally managed by their administrator. If the administrator enables application settings persistence for the pool, users can configure certain application settings, such as browser favorites, plugins, and UI customizations. Users can also access persistent file or object storage external to the desktop.

These desktops are a great fit for many types of users and use cases including remote workers, task workers (shared service centers, finance, procurement, HR, and so forth), contact center workers, and students.

As the administrator for the pool, you have full control over the compute resources (bundle type) and the initial configuration of the desktops in the pool, including the set of applications that are available to the users. You can use an existing custom WorkSpaces image, create a new one, or use one of the standard ones. You can also include Microsoft 365 Apps for Enterprise on the image. You can configure the pool to accommodate the size and working hours of your user base, and you can optionally join the pool to your organization’s domain and active directory.

Getting started
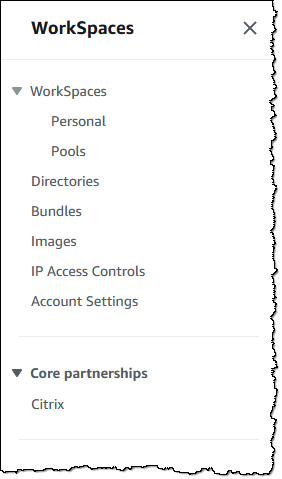
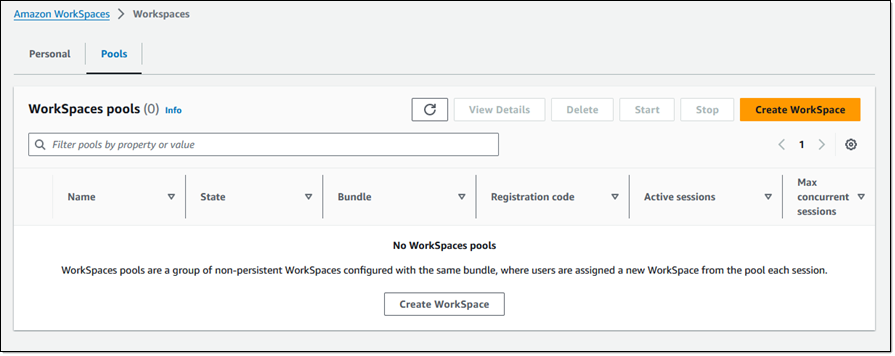
Let’s walk through the process of setting up a pool and inviting some users. I open the WorkSpaces console and choose Pools to get started:

I have no pools, so I choose Create WorkSpace on the Pools tab to begin the process of creating a pool:

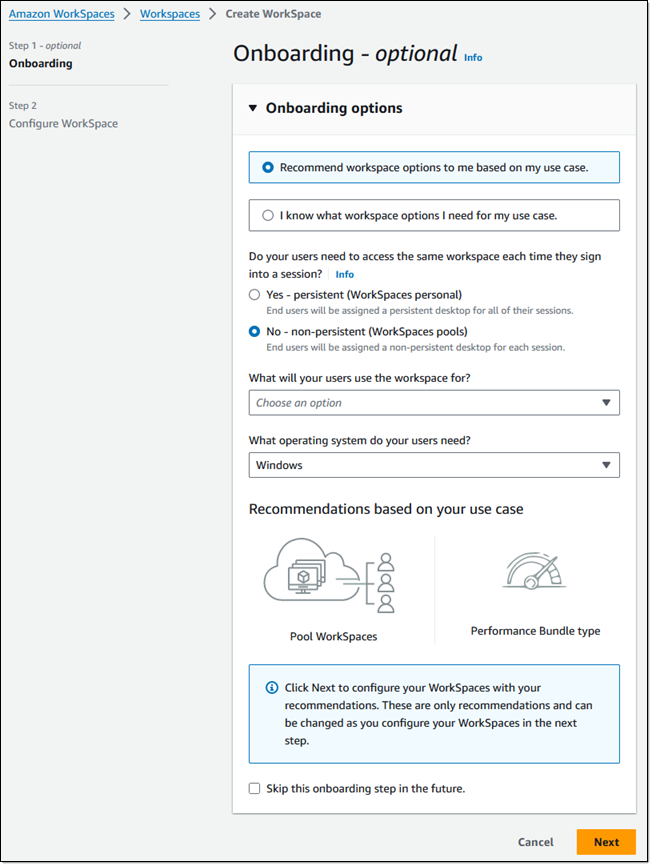
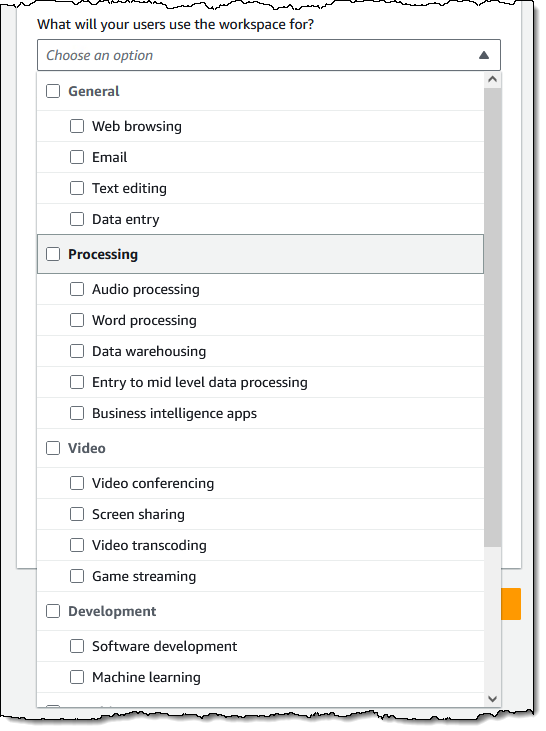
The console can recommend workspace options for me, or I can choose what I want. I leave Recommend workspace options… selected, and choose No – non-persistent to create a pool of non-persistent desktops. Then I select my use cases from the menu and pick the operating system and choose Next to proceed:

The use case menu has lots of options:

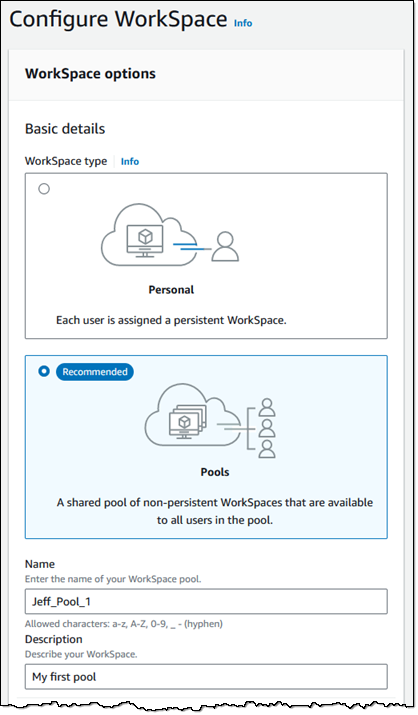
On the next page I start by reviewing the WorkSpace options and assigning a name to my pool:

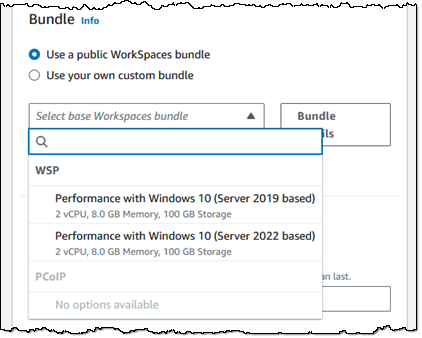
Next, I scroll down and choose a bundle. I can pick a public bundle or a custom one of my own. Bundles must use the WSP 2.0 protocol. I can create a custom bundle to provide my users with access to applications or to alter any desired system settings.

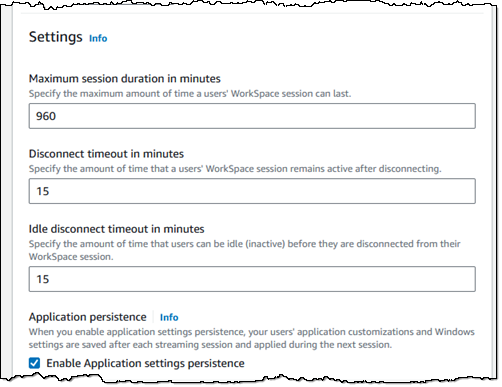
Moving right along, I can customize the settings for each user session. I can also enable application settings persistence to save application customizations and Windows settings on a per-user basis between sessions:

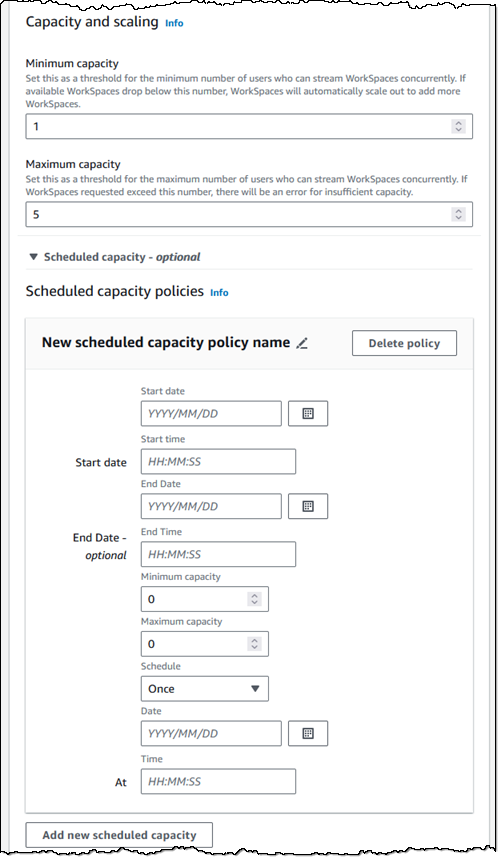
Next, I set the capacity of my pool, and optionally establish one or more schedules based on date or time. The schedules give me the power to match the size of my pool (and hence my costs) to the rhythms and needs of my users:

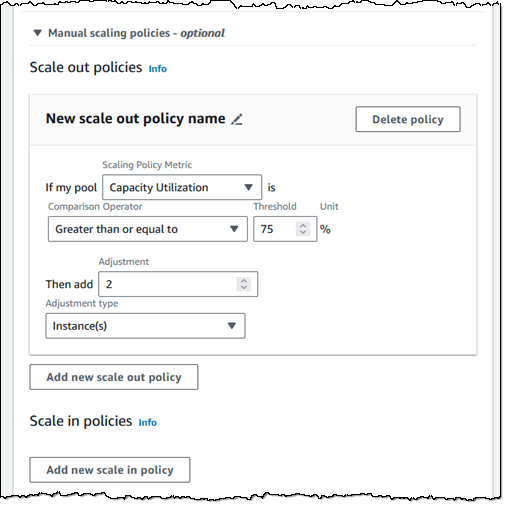
If the amount of concurrent usage is more dynamic and not aligned to a schedule, then I can use manual scale out and scale in policies to control the size of my pool:


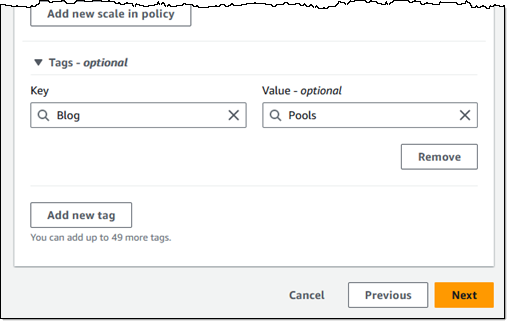
I tag my pool, and then choose Next to proceed:

The final step is to select a WorkSpaces pool directory or create a new one following these steps. Then, I choose Create WorkSpace pool.

WorkSpaces Pools Directory

After the pool has been created and started, I can send registration codes to users, and they can log in to a WorkSpace:

WorkSpaces Pools Login with Registration Code

I can monitor the status of the pool from the console:

WorkSpaces Pool Status On Console

Things to know
Here are a couple of things that you should know about WorkSpaces Pools:

Programmatic access – You can automate the setup process that I showed above by using functions like CreateWorkSpacePool, DescribeWorkSpacePool, UpdateWorkSpacePool, or the equivalent AWS command line interface (CLI) commands.

Regions – WorkSpaces Pools is available in all commercial AWS Regions where WorkSpaces Personal is available, except Israel (Tel Aviv), Africa (Cape Town), and China (Ningxia). Check the full Region list for future updates.

Pricing – Refer to the Amazon WorkSpaces Pricing page for complete pricing information.

Visit Amazon WorkSpaces Pools to learn more.

— Jeff;

Introducing end-to-end data lineage (preview) visualization in Amazon DataZone

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/introducing-end-to-end-data-lineage-preview-visualization-in-amazon-datazone/

Amazon DataZone is a data management service to catalog, discover, analyze, share, and govern data between data producers and consumers in your organization. Engineers, data scientists, product managers, analysts, and business users can easily access data throughout your organization using a unified data portal so that they can discover, use, and collaborate to derive data-driven insights.

Now, I am excited to announce in preview a new API-driven and OpenLineage compatible data lineage capability in Amazon DataZone, which provides an end-to-end view of data movement over time. Data lineage is a new feature within Amazon DataZone that helps users visualize and understand data provenance, trace change management, conduct root cause analysis when a data error is reported, and be prepared for questions on data movement from source to target. This feature provides a comprehensive view of lineage events, captured automatically from Amazon DataZone’s catalog along with other events captured programmatically outside of Amazon DataZone by stitching them together for an asset.

When you need to validate how the data of interest originated in the organization, you may rely on manual documentation or human connections. This manual process is time-consuming and can result in inconsistency, which directly reduces your trust in the data. Data lineage in Amazon DataZone can raise trust by helping you understand where the data originated, how it has changed, and its consumption in time. For example, data lineage can be programmatically setup to show the data from the time it was captured as raw files in Amazon Simple Storage Service (Amazon S3), through its ETL transformations using AWS Glue, to the time it was consumed in tools such as Amazon QuickSight.

With Amazon DataZone’s data lineage, you can reduce the time spent mapping a data asset and its relationships, troubleshooting and developing pipelines, and asserting data governance practices. Data lineage helps you gather all lineage information in one place using API, and then provide a graphical view with which data users can be more productive, make better data-driven decisions, and also identify the root cause of data issues.

Let me tell you how to get started with data lineage in Amazon DataZone. Then, I will show you how data lineage enhances the Amazon DataZone data catalog experience by visually displaying connections about how a data asset came to be so you can make informed decisions when searching or using the data asset.

Getting started with data lineage in Amazon DataZone
In preview, I can get started by hydrating lineage information into Amazon DataZone programmatically by either directly creating lineage nodes using Amazon DataZone APIs or by sending OpenLineage compatible events from existing pipeline components to capture data movement or transformations that happens outside of Amazon DataZone. For information about assets in the catalog, Amazon DataZone automatically captures lineage of its states (i.e., inventory or published states), and its subscriptions for producers, such as data engineers, to trace who is consuming the data they produced or for data consumers, such as data analyst or data engineers, to understand if they are using the right data for their analysis.

With the information being sent, Amazon DataZone will start populating the lineage model and will be able to map the identifier sent through the APIs with the assets already cataloged. As new lineage information is being sent, the model starts creating versions to start the visualization of the asset at a given time, but it also allows me to navigate to previous versions.

I use a preconfigured Amazon DataZone domain for this use case. I use Amazon DataZone domains to organize my data assets, users, and projects. I go to the Amazon DataZone console and choose View domains. I choose my domain Sales_Domain and choose Open data portal.

I have five projects under my domain: one for a data producer (SalesProject) and four for data consumers (MarketingTestProject, AdCampaignProject, SocialCampaignProject, and WebCampaignProject). You can visit Amazon DataZone Now Generally Available – Collaborate on Data Projects across Organizational Boundaries to create your own domain and all the core components.

I enter “Market Sales Table” in the Search Assets bar and then go to the detail page for the Market Sales Table asset. I choose the LINEAGE tab to visualize lineage with upstream and downstream nodes.

I can now dive into asset details, processes, or jobs that lead to or from those assets and drill into column-level lineage.

Interactive visualization with data lineage
I will show you the graphical interface using various personas who regularly interact with Amazon DataZone and will benefit from the data lineage feature.

First, let’s say I am a marketing analyst, who needs to confirm the origin of a data asset to confidently use in my analysis. I go to the MarketingTestProject page and choose the LINEAGE tab. I notice the lineage includes information about the asset as it occurs inside and out of Amazon DataZone. The labels Cataloged, Published, and Access requested represent actions inside the catalog. I expand the market_sales dataset item to see where the data came from.

I now feel assured of the origin of the data asset and trust that it aligns with my business purpose ahead of starting my analysis.

Second, let’s say I am a data engineer. I need to understand the impact of my work on dependent objects to avoid unintended changes. As a data engineer, any changes made to the system should not break any downstream processes. By browsing lineage, I can clearly see who has subscribed and has access to the asset. With this information, I can inform the project teams about an impending change that can affect their pipeline. When a data issue is reported, I can investigate each node and traverse between its versions to dive into what has changed over time to identify the root cause of the issue and fix it in a timely manner.

Finally, as an administrator or steward, I am responsible for securing data, standardizing business taxonomies, enacting data management processes, and for general catalog management. I need to collect details about the source of data and understand the transformations that have happened along the way.

For example, as an administrator looking to respond to questions from an auditor, I traverse the graph upstream to see where the data is coming from and notice that the data is from two different sources: online sale and in-store sale. These sources have their own pipelines until the flow reaches a point where the pipelines merge.

While navigating through the lineage graph, I can expand the columns to ensure sensitive columns are dropped during the transformation processes and respond to the auditors with details in a timely manner.

Join the preview
Data lineage capability is available in preview in all Regions where Amazon DataZone is generally available. For a list of Regions where Amazon DataZone domains can be provisioned, visit AWS Services by Region.

Data lineage costs are dependent on storage usage and API requests, which are already included in Amazon DataZone’s pricing model. For more details, visit Amazon DataZone pricing.

To learn more about data lineage in Amazon DataZone, visit the Amazon DataZone User Guide.

— Esra

Amazon CodeCatalyst now supports GitLab and Bitbucket repositories, with blueprints and Amazon Q feature development

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-codecatalyst-now-supports-gitlab-and-bitbucket-repositories-with-blueprints-and-amazon-q-feature-development/

I’m happy to announce that we’re further integrating Amazon CodeCatalyst with two popular code repositories: GitLab and BitBucket, in addition to the existing integration with GitHub. We bring the same set of capabilities that you use today on CodeCatalyst with GitHub to GitLab.com and Bitbucket Cloud.

Amazon CodeCatalyst is a unified software development and delivery service. It enables software development teams to quickly and easily plan, develop, collaborate on, build, and deliver applications on Amazon Web Services (AWS), reducing friction throughout the development lifecycle.

The GitHub, GitLab.com, and Bitbucket Cloud repositories extension for CodeCatalyst simplifies managing your development workflow. The extension allows you to view and manage external repositories directly within CodeCatalyst. Additionally, you can store and manage workflow definition files alongside your code in external repositories while also creating, reading, updating, and deleting files in linked repositories from CodeCatalyst dev environments. The extension also triggers CodeCatalyst workflow runs automatically upon code pushes and when pull requests are opened, merged, or closed. Furthermore, it allows you to directly utilize source files from linked repositories and execute actions within CodeCatalyst workflows, eliminating the need to switch platforms and maximizing efficiency.

But there’s more: starting today, you can create a CodeCatalyst project in a GitHub, GitLab.com, or Bitbucket Cloud repository from a blueprint, you can add a blueprint to an existing code base in a repository on any of those three systems, and you can also create custom blueprints stored in your external repositories hosted on GitHub, GitLab.com, or Bitbucket Cloud.

CodeCatalyst blueprints help to speed up your developments. These pre-built templates provide a source repository, sample code, continuous integration and delivery (CI/CD) workflows, and integrated issue tracking to get you started quickly. Blueprints automatically update with best practices, keeping your code modern. IT leaders can create custom blueprints to standardize development for your team, specifying technology, access controls, deployment, and testing methods. And now, you can use blueprints even if your code resides in GitHub, GitLab.com, or Bitbucket Cloud.

Link your CodeCatalyst space with a git repository hosting service
Getting started using any of these three source code repository providers is easy. As a CodeCatalyst space administrator, I select the space where I want to configure the extensions. Then, I select Settings, and in the Installed extensions section, I select Configure to link my CodeCatalyst space with my GitHub, GitLab.com, or Bitbucket Cloud account.

Link CodeCatalyst with a git repository hosting service

This is a one-time operation for each CodeCatalyst space, but you might want to connect your space to multiple source providers’ accounts.

When using GitHub, I also have to link my personal CodeCatalyst user to my GitHub user. Under my personal menu on the top right side of the screen, I select My settings. Then, I navigate down to the Personal connections section. I select Create and follow the instructions to authenticate on GitHub and link my two identities.

Link personal CodeCatalyst account to your git hosting provider account

This is a one-time operation for each user in the CodeCatalyst space. This is only required when you’re using GitHub with blueprints.

Create a project from a blueprint and host it on GitHub, GitLab.com, and Bitbucket Cloud
Let’s show you how to create a project in an external repository from a blueprint and later add other blueprints to this project. You can use any of the three git hosting providers supported by CodeCatalyst. In this demo, I chose to use GitHub.

Let’s imagine I want to create a new project to implement an API. I start from a blueprint that implements an API with Python and the AWS Serverless Application Model (AWS SAM). The blueprint also creates a CI workflow and an issue management system. I want my project code to be hosted on GitHub. It allows me to directly use source files from my repository in GitHub and execute actions within CodeCatalyst workflows, eliminating the need to switch platforms.

I start by selecting Create project on my CodeCatalyst space page. I select Start with a blueprint and select the CodeCatalyst blueprint or Space blueprint I want to use. Then, I select Next.

Amazon CodeCatalyst create project from blueprint

I enter a name for my project. I open the Advanced section, and I select GitHub as Repository provider and my GitHub account. You can configure additional connections to GitHub by selecting Connect a GitHub account.

Amazon CodeCatalyst - select a github account

The rest of the configuration depends on the selected blueprint. In this case, I chose the language version, the AWS account to deploy the project to, the name of the AWS Lambda function, and the name of the AWS CloudFormation stack.

After the project is created, I navigate to my GitHub account, and I can see that a new repository has been created. It contains the code and resources from the blueprint.

Amazon CodeCatalyst - creation f new GitHub repository

Add a blueprint to an existing GitHub, GitLab.com, or Bitbucket Cloud project
You can apply multiple blueprints in a project to incorporate functional components, resources, and governance to existing CodeCatalyst projects. Your projects can support various elements that are managed independently in separate blueprints. The service documentation helps you learn more about lifecycle management with blueprints on existing projects.

I can now add a blueprint to an existing project in an external source code repository. Now that my backend API project has been created, I want to add a web application to my project.

I navigate to the Blueprints section in the left-side menu, and I select the orange Add blueprint button on the top-right part of the screen.

CodeCatalyst - add blue print to an existing project

I select the Single-page application blueprint and select Next.

On the next screen, I make sure to select my GitHub connection, as I did when I created the project. I also fill in the required information for this specific template. On the right side of the screen, I review the proposed changes.

CodeCatalyst - add a blueprint to a project in GitHub

Similarly, when using CodeCatalyst Enterprise Tier, I can create my own custom blueprints to share with my teammates or other groups within my organization. For brevity, I don’t share step-by-step instructions to do so in this post. For more information, see Standardizing projects with custom blueprints in the documentation.

When CodeCatalyst finishes installing the new blueprint, I can see a second repository on GitHub.

Amazon CodeCatalyst - multiple repositories

Single or multiple repository strategies
When organizing code, you can choose between a single large repository, like a toolbox overflowing with everything, or splitting it into smaller, specialized ones for better organization. Single repositories simplify dependency management for tightly linked projects but can become messy at scale. Multiple repositories offer cleaner organization and improved security but require planning to manage dependencies between separate projects.

CodeCatalyst lets you use the best strategy for your project. For more information, see the section Store and collaborate on code with source repositories in CodeCatalyst in the documentation.

In the example I showed before, the blueprint I selected proposed to apply the second blueprint as a separate repository in GitHub. Depending on the blueprint you selected, the blueprint may propose that you create a separate repository or merge the new code in an existing repository. In the latter case, the blueprint will submit a pull request for you to merge into your repository.

Region and availability
This new GitHub integration is available at no additional cost in the two AWS Regions where Amazon CodeCatalyst is available, US West (Oregon) and Europe (Ireland) at the time of publication.

Try it now!

— seb

Optimizing Amazon Simple Queue Service (SQS) for speed and scale

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/optimizing-amazon-simple-queue-service-sqs-for-speed-and-scale/

After several public betas, we launched Amazon Simple Queue Service (Amazon SQS) in 2006. Nearly two decades later, this fully managed service is still a fundamental building block for microservices, distributed systems, and serverless applications, processing over 100 million messages per second at peak times.

Because there’s always a better way, we continue to look for ways to improve performance, security, internal efficiency, and so forth. When we do find a potential way to do something better, we are careful to preserve existing behavior, and often run new and old systems in parallel to allow us to compare results.

Today I would like to tell you how we recently made improvements to Amazon SQS to reduce latency, increase fleet capacity, mitigate an approaching scalability cliff, and reduce power consumption.

Improving SQS
Like many AWS services, Amazon SQS is implemented using a collection of internal microservices. Let’s focus on two of them today:

Customer Front-End – The customer-facing front-end accepts, authenticates, and authorizes API calls such as CreateQueue and SendMessage. It then routes each request to the storage back-end.

Storage Back-End -This internal microservice is responsible for persisting messages sent to standard (non-FIFO) queues. Using a cell-based model, each cluster in the cell contains multiple hosts, each customer queue is assigned to one or more clusters, and each cluster is responsible for a multitude of queues:

Connections – Old and New
The original implementation used a connection per request between these two services. Each front-end had to connect to many hosts, which mandated the use of a connection pool, and also risked reaching an ultimate, hard-wired limit on the number of open connections. While it is often possible to simply throw hardware at problems like this and scale out, that’s not always the best way. It simply moves the moment of truth (the “scalability cliff”) into the future and does not make efficient use of resources.

After carefully considering several long-term solutions, the Amazon SQS team invented a new, proprietary binary framing protocol between the customer front-end and storage back-end. The protocol multiplexes multiple requests and responses across a single connection, using 128-bit IDs and checksumming to prevent crosstalk. Server-side encryption provides an additional layer of protection against unauthorized access to queue data.

It Works!
The new protocol was put into production earlier this year and has processed 744.9 trillion requests as I write this. The scalability cliff has been eliminated and we are already looking for ways to put this new protocol to work in other ways.

Performance-wise, the new protocol has reduced dataplane latency by 11% on average, and by 17.4% at the P90 mark. In addition to making SQS itself more performant, this change benefits services that build on SQS as well. For example, messages sent through Amazon Simple Notification Service (Amazon SNS) now spend 10% less time “inside” before being delivered. Finally, due to the protocol change, the existing fleet of SQS hosts (a mix of X86 and Graviton-powered instances) can now handle 17.8% more requests than before.

More to Come
I hope that you have enjoyed this little peek inside the implementation of Amazon SQS. Let me know in the comments, and I will see if I can find some more stories to share.

— Jeff;

AWS Weekly Roundup: Claude 3.5 Sonnet in Amazon Bedrock, CodeCatalyst updates, SageMaker with MLflow, and more (June 24, 2024)

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-3-5-sonnet-in-amazon-bedrock-codecatalyst-updates-sagemaker-with-mlflow-and-more-june-24-2024/

This week, I had the opportunity to try the new Anthropic Claude 3.5 Sonnet model in Amazon Bedrock just before it launched, and I was really impressed by its speed and accuracy! It was also the week of AWS Summit Japan; here’s a nice picture of the busy AWS Community stage.

AWS Community stage at the AWS Summit Tokyo

Last week’s launches
With many new capabilities, from recommendations on the size of your Amazon Relational Database Services (Amazon RDS) databases to new built-in transformations in AWS Glue, here’s what got my attention:

Amazon Bedrock – Now supports Anthropic’s Claude 3.5 Sonnet and compressed embeddings from Cohere Embed.

AWS CodeArtifact – With support for Rust packages with Cargo, developers can now store and access their Rust libraries (known as crates).

Amazon CodeCatalyst – Many updates from this unified software development service. You can now assign issues in CodeCatalyst to Amazon Q and direct it to work with source code hosted in GitHub Cloud and Bitbucket Cloud and ask Amazon Q to analyze issues and recommend granular tasks. These tasks can then be individually assigned to users or to Amazon Q itself. You can now also use Amazon Q to help pick the best blueprint for your needs. You can now securely store, publish, and share Maven, Python, and NuGet packages. You can also link an issue to other issues. This allows customers to link issues in CodeCatalyst as blocked by, duplicate of, related to, or blocks another issue. You can now configure a single CodeBuild webhook at organization or enterprise level to receive events from all repositories in your organizations, instead of creating webhooks for each individual repository. Finally, you can now add a default IAM role to an environment.

Amazon EC2 – C7g and R7g instances (powered by AWS Graviton3 processors) are now available in Europe (Milan), Asia Pacific (Hong Kong), and South America (São Paulo) Regions. C7i-flex instances are now available in US East (Ohio) Region.

AWS Compute Optimizer – Now provides rightsizing recommendations for Amazon RDS MySQL, and RDS PostgreSQL. More info in this Cloud Financial Management blog post.

Amazon OpenSearch Service – With JSON Web Token (JWT) authentication and authorization, it’s now easier to integrate identity providers and isolate tenants in a multi-tenant application.

Amazon SageMaker – Now helps you manage machine learning (ML) experiments and the entire ML lifecycle with a fully managed MLflow capability.

AWS Glue – The serverless data integration service now offers 13 new built-in transforms: flag duplicates in column, format Phone Number, format case, fill with mode, flag duplicate rows, remove duplicates, month name, iIs even, cryptographic hash, decrypt, encrypt, int to IP, and IP to int.

Amazon MWAA – Amazon Managed Workflows for Apache Airflow (MWAA) now supports custom domain names for the Airflow web server, allowing to use private web servers with load balancers, custom DNS entries, or proxies to point users to a user-friendly web address.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS news
Here are some additional projects, blog posts, and news items that you might find interesting:

AWS re:Inforce 2024 re:Cap – A summary of our annual, immersive, cloud-security learning event by my colleague Wojtek.

Three ways Amazon Q Developer agent for code transformation accelerates Java upgrades – This post offers interesting details on how Amazon Q Developer handles major version upgrades of popular frameworks, replacing deprecated API calls on your behalf, and explainability on code changes.

Five ways Amazon Q simplifies AWS CloudFormation development – For template code generation, querying CloudFormation resource requirements, explaining existing template code, understanding deployment options and issues, and querying CloudFormation documentation.

Improving air quality with generative AI – A nice solution that uses artificial intelligence (AI) to standardize air quality data, addressing the air quality data integration problem of low-cost sensors.

Deploy a Slack gateway for Amazon Bedrock – A solution bringing the power of generative AI directly into your Slack workspace.

An agent-based simulation of Amazon’s inbound supply chain – Simulating the entire US inbound supply chain, including the “first-mile” of distribution and tracking the movement of hundreds of millions of individual products through the network.

AWS CloudFormation Linter (cfn-lint) v1 – This upgrade is particularly significant because it converts from using the CloudFormation spec to using CloudFormation registry resource provider schemas.

A practical approach to using generative AI in the SDLC – Learn how an AI assistant like Amazon Q Developer helps my colleague Jenna figure out what to build and how to build it.

AWS open source news and updates – My colleague Ricardo writes about open source projects, tools, and events from the AWS Community. Check out Ricardo’s page for the latest updates.

Upcoming AWS events
Check your calendars and sign up for upcoming AWS events:

AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. This week, you can join the AWS Summit in Washington, DC, June 26–27. Learn here about future AWS Summit events happening in your area.

AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world. This week there are AWS Community Days in Switzerland (June 27), Sri Lanka (June 27), and the Gen AI Edition in Ahmedabad, India (June 29).

Browse all upcoming AWS led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Danilo

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

AWS CodeArtifact adds support for Rust packages with Cargo

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-codeartifact-adds-support-for-rust-packages-with-cargo/

Starting today, Rust developers can store and access their libraries (known as crates in Rust’s world) on AWS CodeArtifact.

Modern software development relies heavily on pre-written code packages to accelerate development. These packages, which can number in the hundreds for a single application, tackle common programming tasks and can be created internally or obtained from external sources. While these packages significantly help to speed up development, their use introduces two main challenges for organizations: legal and security concerns.

On the legal side, organizations need to ensure they have compatible licenses for these third-party packages and that they don’t infringe on intellectual property rights. Security is another risk, as vulnerabilities in these packages could be exploited to compromise an application. A known tactic, the supply chain attack, involves injecting vulnerabilities into popular open source projects.

To address these challenges, organizations can set up private package repositories. These repositories store pre-approved packages vetted by security and legal teams, limiting the risk of legal or security exposure. This is where CodeArtifact enters.

AWS CodeArtifact is a fully managed artifact repository service designed to securely store, publish, and share software packages used in application development. It supports popular package managers and formats such as npm, PyPI, Maven, NuGet, SwiftPM, and Rubygem, enabling easy integration into existing development workflows. It helps enhance security through controlled access and facilitates collaboration across teams. CodeArtifact helps maintain a consistent, secure, and efficient software development lifecycle by integrating with AWS Identity and Access Management (IAM) and continuous integration and continuous deployment (CI/CD) tools.

For the eighth year in a row, Rust has topped the chart as “the most desired programming language” in Stack Overflow’s annual developer survey, with more than 80 percent of developers reporting that they’d like to use the language again next year. Rust’s growing popularity stems from its ability to combine the performance and memory safety of systems languages such as C++ with features that makes writing reliable, concurrent code easier. This, along with a rich ecosystem and a strong focus on community collaboration, makes Rust an attractive option for developers working on high-performance systems and applications.

Rust developers rely on Cargo, the official package manager, to manage package dependencies. Cargo simplifies the process of finding, downloading, and integrating pre-written crates (libraries) into their projects. This not only saves time by eliminating manual dependency management, but also ensures compatibility and security. Cargo’s robust dependency resolution system tackles potential conflicts between different crate versions, and because many crates come from a curated registry, developers can be more confident about the code’s quality and safety. This focus on efficiency and reliability makes Cargo an essential tool for building Rust applications.

Let’s create a CodeArtifact repository for my crates
In this demo, I use the AWS Command Line Interface (AWS CLI) and AWS Management Console to create two repositories. I configure the first repository to download public packages from the official crates.io repository. I configure the second repository to download packages from the first one only. This dual repository configuration is the recommended way to manage repositories and external connections, see the CodeArtifact documentation for managing external connections. To quote the documentation:

“It is recommended to have one repository per domain with an external connection to a given public repository. To connect other repositories to the public repository, add the repository with the external connection as an upstream to them.”

I sketched this diagram to illustrate the setup.

Code Artifact repositories for cargo

Domains and repositories can be created either from the command line or the console. I choose the command line. In shell terminal, I type:

CODEARTIFACT_DOMAIN=stormacq-test

# Create an internal-facing repository: crates-io-store
aws codeartifact create-repository \
   --domain $CODEARTIFACT_DOMAIN   \
   --repository crates-io-store

# Associate the internal-facing repository crates-io-store to the public crates-io
aws codeartifact associate-external-connection \
--domain $CODEARTIFACT_DOMAIN \
--repository crates-io-store  \
--external-connection public:crates-io

# Create a second internal-facing repository: cargo-repo 
# and connect it to upstream crates-io-store just created
aws codeartifact create-repository \
   --domain $CODEARTIFACT_DOMAIN   \
   --repository cargo-repo         \
   --upstreams '{"repositoryName":"crates-io-store"}'	 

Next, as a developer, I want my local machine to fetch crates from the internal repository (cargo-repo) I just created.

I configure cargo to fetch libraries from the internal repository instead of the public crates.io. To do so, I create a config.toml file to point to CodeArtifact internal repository.

# First, I retrieve the URI of the repo
REPO_ENDPOINT=$(aws codeartifact get-repository-endpoint \
                           --domain $CODEARTIFACT_DOMAIN \ 
                           --repository cargo-repo       \
                           --format cargo                \
                           --output text)

# at this stage, REPO_ENDPOINT is https://stormacq-test-012345678912.d.codeartifact.us-west-2.amazonaws.com/cargo/cargo-repo/

# Next, I create the cargo config file
cat << EOF > ~/.cargo/config.toml
[registries.cargo-repo]
index = "sparse+$REPO_ENDPOINT"
credential-provider = "cargo:token-from-stdout aws codeartifact get-authorization-token --domain $CODEARTIFACT_DOMAIN --query authorizationToken --output text"

[registry]
default = "cargo-repo"

[source.crates-io]
replace-with = "cargo-repo"
EOF

Note that the two environment variables are replaced when I create the config file. cargo doesn’t support environment variables in its configuration.

From now on, on this machine, every time I invoke cargo to add a crate, cargo will obtain an authorization token from CodeArtifact to communicate with the internal cargo-repo repository. I must have IAM privileges to call the get-authorization-token CodeArtifact API in addition to permissions for read/publish package according to the command I use. If you’re running this setup from a build machine for your continuous integration (CI) pipeline, your build machine must have proper permissions to do so.

I can now test this setup and add a crate to my local project.

$ cargo add regex
    Updating `codeartifact` index
      Adding regex v1.10.4 to dependencies
             Features:
             + perf
             + perf-backtrack
             + perf-cache
             + perf-dfa
             + perf-inline
             + perf-literal
             + perf-onepass
             + std
             + unicode
             + unicode-age
             + unicode-bool
             + unicode-case
             + unicode-gencat
             + unicode-perl
             + unicode-script
             + unicode-segment
             - logging
             - pattern
             - perf-dfa-full
             - unstable
             - use_std
    Updating `cargo-repo` index

# Build the project to trigger the download of the crate
$ cargo build
  Downloaded memchr v2.7.2 (registry `cargo-repo`)
  Downloaded regex-syntax v0.8.3 (registry `cargo-repo`)
  Downloaded regex v1.10.4 (registry `cargo-repo`)
  Downloaded aho-corasick v1.1.3 (registry `cargo-repo`)
  Downloaded regex-automata v0.4.6 (registry `cargo-repo`)
  Downloaded 5 crates (1.5 MB) in 1.99s
   Compiling memchr v2.7.2 (registry `cargo-repo`)
   Compiling regex-syntax v0.8.3 (registry `cargo-repo`)
   Compiling aho-corasick v1.1.3 (registry `cargo-repo`)
   Compiling regex-automata v0.4.6 (registry `cargo-repo`)
   Compiling regex v1.10.4 (registry `cargo-repo`)
   Compiling hello_world v0.1.0 (/home/ec2-user/hello_world)
    Finished `dev` profile [unoptimized + debuginfo] target(s) in 16.60s

I can verify CodeArtifact downloaded the crate and its dependencies from the upstream public repository. I connect to the CodeArtifact console and check the list of packages available in either repository I created. At this stage, the package list should be identical in the two repositories.

CodeArtifact cargo packages list

Publish a private package to the repository
Now that I know the upstream link works as intended, let’s publish a private package to my cargo-repo repository to make it available to other teams in my organization.

To do so, I use the standard Rust tool cargo, just like usual. Before doing so, I add and commit the project files to the gitrepository.

$  git add . && git commit -m "initial commit"
 5 files changed, 1855 insertions(+)
create mode 100644 .gitignore
create mode 100644 Cargo.lock
create mode 100644 Cargo.toml
create mode 100644 commands.sh
create mode 100644 src/main.rs

$  cargo publish 
    Updating `codeartifact` index
   Packaging hello_world v0.1.0 (/home/ec2-user/hello_world)
    Updating crates.io index
    Updating `codeartifact` index
   Verifying hello_world v0.1.0 (/home/ec2-user/hello_world)
   Compiling libc v0.2.155
... (redacted for brevity) ....
   Compiling hello_world v0.1.0 (/home/ec2-user/hello_world/target/package/hello_world-0.1.0)
    Finished `dev` profile [unoptimized + debuginfo] target(s) in 1m 03s
    Packaged 5 files, 44.1KiB (11.5KiB compressed)
   Uploading hello_world v0.1.0 (/home/ec2-user/hello_world)
    Uploaded hello_world v0.1.0 to registry `cargo-repo`
note: waiting for `hello_world v0.1.0` to be available at registry `cargo-repo`.
You may press ctrl-c to skip waiting; the crate should be available shortly.
   Published hello_world v0.1.0 at registry `cargo-repo`

Lastly, I use the console to verify the hello_world crate is now available in the cargo-repo.

CodeArtifact cargo package hello world

Pricing and availability
You can now store your Rust libraries in the 13 AWS Regions where CodeArtifact is available. There is no additional cost for Rust packages. The three billing dimensions are the storage (measured in GB per month), the number of requests, and the data transfer out to the internet or to other AWS Regions. Data transfer to AWS services in the same Region is not charged, meaning you can run your continuous integration and delivery (CI/CD) jobs on Amazon Elastic Compute Cloud (Amazon EC2) or AWS CodeBuild, for example, without incurring a charge for the CodeArtifact data transfer. As usual, the pricing page has the details.

Now go build your Rust applications and upload your private crates to CodeArtifact!

— seb

Anthropic’s Claude 3.5 Sonnet model now available in Amazon Bedrock: Even more intelligence than Claude 3 Opus at one-fifth the cost

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/anthropics-claude-3-5-sonnet-model-now-available-in-amazon-bedrock-the-most-intelligent-claude-model-yet/

It’s been just 3 months since Anthropic launched Claude 3, a family of state-of-the-art artificial intelligence (AI) models that allows you to choose the right combination of intelligence, speed, and cost that suits your needs.

Today, Anthropic introduced Claude 3.5 Sonnet, its first release in the forthcoming Claude 3.5 model family. We are happy to announce that Claude 3.5 Sonnet is now available in Amazon Bedrock.

Claude 3.5 Sonnet raises the industry bar for intelligence, outperforming other generative AI models on a wide range of evaluations, including Anthropic’s previously most intelligent model, Claude 3 Opus. Claude 3.5 Sonnet is available with the speed and cost of the original Claude 3 Sonnet model. In fact, you can now get intelligence and speed better than Claude 3 Opus at one-fifth of the price because Claude 3.5 Sonnet is 80 percent cheaper than Opus.

Anthropic Claude 3.5 Sonnet Family

The frontier intelligence displayed by Claude 3.5 Sonnet combined with cost-effective pricing, makes the model ideal for complex tasks such as context-sensitive customer support, orchestrating multi-step workflows, and streamlining code translations.

Claude 3.5 Sonnet sets new industry benchmarks for undergraduate-level expert knowledge (MMLU), graduate-level expert reasoning (GPQA), code (HumanEval), and more. As you can see in the following table, according to Anthropic, Claude 3.5 Sonnet outperforms OpenAI’s GPT-4o and Google’s Gemini 1.5 Pro in nearly every benchmark.

Anthropic Claude 3.5 Sonnet Benchmarks

Claude 3.5 Sonnet is also Anthropic’s strongest vision model yet, performing an average of 10 percent better than Claude 3 Opus across the majority of vision benchmarks. According to Anthropic, Claude 3.5 Sonnet also outperforms other generative AI models in nearly every category.

Anthropic Claude 3.5 Sonnet Vision Benchmarks

Anthropic’s Claude 3.5 Sonnet key improvements
The release of Claude 3.5 Sonnet brings significant improvements across multiple domains, empowering software developers and businesses with new generative AI-powered capabilities. Here are some of the key strengths of this new model:

Visual processing and understanding – Claude 3.5 Sonnet demonstrates remarkable capabilities in processing images, particularly in interpreting charts and graphs. It accurately transcribes text from imperfect images, a core capability for industries such as retail, logistics, and financial services, to gather more insights from graphics or illustrations than from text alone. Use Claude 3.5 Sonnet to automate visual data processing tasks, extract valuable information, and enhance data analysis pipelines.

Writing and content generation – Claude 3.5 Sonnet represents a significant leap in its ability to understand nuance and humor. The model produces high-quality written content with a more natural, human tone that feels more authentic and relatable. Use the model to generate engaging and compelling content, streamline your writing workflows, and enhance your storytelling capabilities.

Customer support and natural language processing – With its improved understanding of context and multistep workflow orchestration, Claude 3.5 Sonnet excels at handling intricate customer inquiries. This capability enables round-the-clock support, faster response times, and more natural-sounding interactions, ultimately leading to improved customer satisfaction. Use this model to automate and enhance customer support processes and provide a seamless experience for end users. For an example of a similar implementation, see how DoorDash built a generative AI self-service contact center solution using Anthropic’s Claude 3 models in Amazon Bedrock.

Analytics and insights – Claude 3.5 Sonnet augments human expertise in data science by effortlessly navigating unstructured data and using multiple tools to generate insights. It produces high-quality statistical visualizations and actionable predictions, ranging from business strategies to real-time product trends. Use Claude 3.5 Sonnet to simplify data analysis workflows, uncover valuable insights, and drive data-driven decision-making.

Coding and software development – Claude 3.5 Sonnet can independently write, edit, and execute code with sophisticated reasoning and troubleshooting capabilities when provided with the relevant tools. Use Claude 3.5 Sonnet to streamline developer workflows, accelerate coding tasks, reduce manual effort, and enhance overall productivity.

Using Anthropic’s Claude 3.5 Sonnet in the Amazon Bedrock console
Because this is a new model, I go to the Amazon Bedrock console and choose Model access from the navigation pane to enable access to Claude 3.5 Sonnet.

Console screenshot.

Now that I have access to the model, I’d like to use it to extract information from the following image from the Our World in Data website:

Primary energy consumption from hydropower, 2022

I choose Chat in the Playgrounds section of the navigation pane and select Anthropic and Claude 3.5 Sonnet as the model. I then choose the Image upload button to upload the previous image, type the following prompt, and choose Run:

Which countries consume more than 1000 TWh from hydropower? Think step by step and look at all regions. Output in JSON.

Here’s the result and an animated image recapping what I did.

To determine which countries consume more than 1,000 TWh from hydropower in 2022, I need to carefully examine the map and color-coding. The scale at the bottom shows that dark blue represents consumption between 1,000 TWh and 2,000 TWh.

Let's look at each region systematically:

1. North America: Canada is dark blue, indicating it consumes between 1,000-2,000 TWh from hydropower.
2. South America: Brazil is dark blue, also consuming between 1,000-2,000 TWh.
3. Europe: No country is dark blue; all are light green or have no data.
4. Africa: No data available for any country.
5. Asia: China is dark blue, indicating consumption between 1,000-2,000 TWh.
6. Oceania: No country is dark blue; Australia is light green.

In summary, there are three countries that consume more than 1,000 TWh from hydropower in 2022:
1. Canada (North America)
2. Brazil (South America)
3. China (Asia)

Here's the response in JSON format:

```json
{
  "countries_consuming_over_1000TWh_hydropower": [
    {
      "name": "Canada",
      "region": "North America",
      "consumption_range": "1,000-2,000 TWh"
    },
    {
      "name": "Brazil",
      "region": "South America",
      "consumption_range": "1,000-2,000 TWh"
    },
    {
      "name": "China",
      "region": "Asia",
      "consumption_range": "1,000-2,000 TWh"
    }
  ]
}
```

These three countries stand out as the highest consumers of hydropower energy, each using between 1,000 and 2,000 terawatt-hours in 2022.

Anthropic's Claude 3.5 Sonnet demo in the Amazon Bedrock console.

The model’s ability to reliably extract information from unstructured data, like images, opens up a world of new possibilities.

I choose the three small dots in the corner of the playground window and then View API request to see code examples using the model in the AWS Command Line Interface (AWS CLI) and AWS SDKs. Let’s have a better look at the code syntax.

Using Claude 3.5 Sonnet with AWS SDKs
You can use Claude 3.5 Sonnet with any AWS SDK using the new Amazon Bedrock Converse API or Anthropic Claude Messages API.

To update code already using a Claude 3 model, I just need to replace the model ID with:

anthropic.claude-3-5-sonnet-20240620-v1:0

Here’s a sample implementation with the AWS SDK for Python (Boto3) using the same image as before to show how to use images and text with the Converse API.

import boto3
from botocore.exceptions import ClientError

MODEL_ID = "anthropic.claude-3-5-sonnet-20240620-v1:0"

IMAGE_NAME = "primary-energy-hydro.png"

bedrock_runtime = boto3.client("bedrock-runtime", region_name="us-east-1")

with open(IMAGE_NAME, "rb") as f:
    image = f.read()

user_message = "Which countries consume more than 1000 TWh from hydropower? Think step by step and look at all regions. Output in JSON."

messages = [
    {
        "role": "user",
        "content": [
            {"image": {"format": "png", "source": {"bytes": image}}},
            {"text": user_message},
        ],
    }
]

response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=messages,
)
response_text = response["output"]["message"]["content"][0]["text"]
print(response_text)

When I run it, I get a similar output as in the console:

Let's approach this step-by-step:

1. First, I'll examine the color scale at the bottom of the map. The darkest blue color represents consumption of 2,000 TWh or more.

2. Now, I'll scan the map region by region:

   North America: Canada is dark blue, indicating over 1,000 TWh.
   South America: Brazil is also dark blue, over 1,000 TWh.
   Europe: No country appears to be dark blue.
   Africa: No country appears to be dark blue.
   Asia: China stands out as dark blue, indicating over 1,000 TWh.
   Oceania: No country appears to be dark blue.

3. To be thorough, I'll double-check for any medium blue countries that might be close to or over 1,000 TWh, but I don't see any that appear to reach that threshold.

4. Based on this analysis, there are three countries that clearly consume more than 1,000 TWh from hydropower.

Now, I'll format the answer in JSON:

```json
{
  "countries_consuming_over_1000TWh_hydropower": [
    "Canada",
    "Brazil",
    "China"
  ]
}
```

This JSON output lists the three countries that visually appear to consume more than 1,000 TWh of primary energy from hydropower according to the 2022 data presented in the map.

Because I didn’t specify a JSON syntax, the two answers use a different format. In your applications, you can describe in the prompt the JSON properties you want or provide a sample to get a standard format in output.

For more examples, see the code samples in the Amazon Bedrock User Guide. For a more advanced use case, here’s a fully functional tool use demo illustrating how to connect a generative AI model with a custom tool or API.

Using Claude 3.5 Sonnet with the AWS CLI
There are times when nothing beats the speed of the command line. This is how you can use the AWS CLI with the new model:

aws bedrock-runtime converse \
    --model-id anthropic.claude-3-5-sonnet-20240620-v1:0 \
    --messages '{"role": "user", "content": [{"text": "Alice has N brothers and she also has M sisters. How many sisters does Alice’s brother have?"}]}' \
    --region us-east-1
    --query output.message.content

In the output, I use the query option to only get the content of the output message:

[
    {
        "text": "Let's approach this step-by-step:\n\n1. First, we need to understand the relationships:\n   - Alice has N brothers\n   - Alice has M sisters\n\n2. Now, let's consider Alice's brother:\n   - He is one of Alice's N brothers\n   - He has the same parents as Alice\n\n3. This means that Alice's brother has:\n   - The same sisters as Alice\n   - One sister more than Alice (because Alice herself is his sister)\n\n4. Therefore, the number of sisters Alice's brother has is:\n   M + 1\n\n   Where M is the number of sisters Alice has.\n\nSo, the answer is: Alice's brother has M + 1 sisters."
    }
]

I copy the text into a small Python program to see it printed on multiple lines:

print("Let's approach this step-by-step:\n\n1. First, we need to understand the relationships:\n   - Alice has N brothers\n   - Alice has M sisters\n\n2. Now, let's consider Alice's brother:\n   - He is one of Alice's N brothers\n   - He has the same parents as Alice\n\n3. This means that Alice's brother has:\n   - The same sisters as Alice\n   - One sister more than Alice (because Alice herself is his sister)\n\n4. Therefore, the number of sisters Alice's brother has is:\n   M + 1\n\n   Where M is the number of sisters Alice has.\n\nSo, the answer is: Alice's brother has M + 1 sisters.")
Let's approach this step-by-step:

1. First, we need to understand the relationships:
   - Alice has N brothers
   - Alice has M sisters

2. Now, let's consider Alice's brother:
   - He is one of Alice's N brothers
   - He has the same parents as Alice

3. This means that Alice's brother has:
   - The same sisters as Alice
   - One sister more than Alice (because Alice herself is his sister)

4. Therefore, the number of sisters Alice's brother has is:
   M + 1

   Where M is the number of sisters Alice has.

So, the answer is: Alice's brother has M + 1 sisters.

Even if this was a quite nuanced question, Claude 3.5 Sonnet got it right and described its reasoning step by step.

Things to know
Anthropic’s Claude 3.5 Sonnet is available in Amazon Bedrock today in the US East (N. Virginia) AWS Region. More information on Amazon Bedrock model support by Region is available in the documentation. View the Amazon Bedrock pricing page to determine the costs for your specific use case.

By providing access to a faster and more powerful model at a lower cost, Claude 3.5 Sonnet makes generative AI easier and more effective to use for many industries, such as:

Healthcare and life sciences – In the medical field, Claude 3.5 Sonnet shows promise in enhancing imaging analysis, acting as a diagnostic assistant for patient triage, and summarizing the latest research findings in an easy-to-digest format.

Financial services – The model can provide valuable assistance in identifying financial trends and creating personalized debt repayment plans tailored to clients’ unique situations.

Legal – Law firms can use the model to accelerate legal research by quickly surfacing relevant precedents and statutes. Additionally, the model can increase paralegal efficiency through contract analysis and assist with drafting standard legal documents.

Media and entertainment – The model can expedite research for journalists, support the creative process of scriptwriting and character development, and provide valuable audience sentiment analysis.

Technology – For software developers, Claude 3.5 Sonnet offers opportunities in rapid application prototyping, legacy code migration, innovative feature ideation, user experience optimization, and identification of friction points.

Education – Educators can use the model to streamline grant proposal writing, develop comprehensive curricula incorporating emerging trends, and receive research assistance through database queries and insight generation.

It’s an exciting time for for generative AI. To start using this new model, see the Anthropic Claude models section of the Amazon Bedrock User Guide. You can also visit our community.aws site to find deep-dive technical content and to discover how our Builder communities are using Amazon Bedrock in their solutions. Let me know what you do with these enhanced capabilities!

— Danilo

Announcing the general availability of fully managed MLflow on Amazon SageMaker

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/manage-ml-and-generative-ai-experiments-using-amazon-sagemaker-with-mlflow/

Today, we are thrilled to announce the general availability of a fully managed MLflow capability on Amazon SageMaker. MLflow, a widely-used open-source tool, plays a crucial role in helping machine learning (ML) teams manage the entire ML lifecycle. With this new launch, customers can now effortlessly set up and manage MLflow Tracking Servers with just a few steps, streamlining the process and boosting productivity.

Data Scientists and ML developers can leverage MLflow to track multiple attempts at training models as runs within experiments, compare these runs with visualizations, evaluate models, and register the best models to a Model Registry. Amazon SageMaker eliminates the undifferentiated heavy lifting required to set up and manage MLflow, providing ML administrators with a quick and efficient way to establish secure and scalable MLflow environments on AWS.

Core components of managed MLflow on SageMaker

The fully managed MLflow capability on SageMaker is built around three core components:

  • MLflow Tracking Server – With just a few steps, you can create an MLflow Tracking Server through the SageMaker Studio UI. This stand-alone HTTP server serves multiple REST API endpoints for tracking runs and experiments, enabling you to begin monitoring your ML experiments efficiently. For more granular security customization, you can also use the AWS Command Line Interface (AWS CLI).
  • MLflow backend metadata store – The metadata store is a critical part of the MLflow Tracking Server, where all metadata related to experiments, runs, and artifacts is persisted. This includes experiment names, run IDs, parameter values, metrics, tags, and artifact locations, ensuring comprehensive tracking and management of your ML experiments.
  • MLflow artifact store – This component provides a storage location for all artifacts generated during ML experiments, such as trained models, datasets, logs, and plots. Utilizing an Amazon Simple Storage Service (Amazon S3) bucket, it offers a customer-managed AWS account for storing these artifacts securely and efficiently.

Benefits of Amazon SageMaker with MLflow

Using Amazon SageMaker with MLflow can streamline and enhance your machine learning workflows:

  • Comprehensive Experiment Tracking: Track experiments in MLflow across local integrated development environments (IDEs), managed IDEs in SageMaker Studio, SageMaker training jobs, SageMaker processing jobs, and SageMaker Pipelines.
  • Full MLflow Capabilities: Use all MLflow experimentation capabilities such as MLflow Tracking, MLflow Evaluations, and MLflow Model Registry, are available to easily compare and evaluate the results of training iterations.
  • Unified Model Governance: Models registered in MLflow automatically appear in the SageMaker Model Registry, offering a unified model governance experience that helps you deploy MLflow models to SageMaker inference without building custom containers.
  • Efficient Server Management: Provision, remove, and upgrade MLflow Tracking Servers as desired using SageMaker APIs or the SageMaker Studio UI. SageMaker manages the scaling, patching, and ongoing maintenance of your tracking servers, without customers needing to manage the underlying infrastructure.
  • Enhanced Security: Secure access to MLflow Tracking Servers using AWS Identity and Access Management (IAM). Write IAM policies to grant or deny access to specific MLflow APIs, ensuring robust security for your ML environments.
  • Effective Monitoring and Governance: Monitor the activity on an MLflow Tracking Server using Amazon EventBridge and AWS CloudTrail to support effective governance of their Tracking Servers.

MLflow Tracking Server prerequisites (environment setup)

  1. Create a SageMaker Studio domain
    You can create a SageMaker Studio domain using the new SageMaker Studio experience.
  2. Configure the IAM execution role
    The MLflow Tracking Server needs an IAM execution role to read and write artifacts to Amazon S3 and register models in SageMaker. You can use the Studio domain execution role as the Tracking Server execution role or you can create a separate role for the Tracking Server execution role. If you choose to create a new role for this, refer to the SageMaker Developer Guide for more details on the IAM role. If you choose to update the Studio domain execution role, refer to the SageMaker Developer Guide for details on what IAM policy the role needs.

Create the MLflow Tracking Server
In the walkthrough, I use the default settings for creating an MLflow Tracking Server, which include the Tracking Server version (2.13.2), the Tracking Server size (Small), and the Tracking Server execution role (Studio domain execution role). The Tracking Server size determines how much usage a Tracking Server will support, and we recommend using a Small Tracking Server for teams of up to 25 users. For more details on Tracking Server configurations, read the SageMaker Developer Guide.

To get started, in your SageMaker Studio domain created during your environment set up detailed earlier, select MLflow under Applications and choose Create.

Next, provide a Name and Artifact storage location (S3 URI) for the Tracking Server.

Creating an MLflow Tracking Server can take up to 25 minutes.


Track and compare training runs
To get started with logging metrics, parameters, and artifacts to MLflow, you need a Jupyter Notebook and your Tracking Server ARN that was assigned during the creation step. You can use the MLflow SDK to keep track of training runs and compare them using the MLflow UI.


To register models from MLflow Model Registry to SageMaker Model Registry, you need the sagemaker-mlflow plugin to authenticate all MLflow API requests made by the MLflow SDK using AWS Signature V4.

  1. Install the MLflow SDK and sagemaker-mlflow plugin
    In your notebook, first install the MLflow SDK and sagemaker-mlflow Python plugin.
    pip install mlflow==2.13.2 sagemaker-mlflow==0.1.0
  2. Track a run in an experiment
    To track a run in an experiment, copy the following code into your Jupyter notebook.

    import mlflow
    import mlflow.sklearn
    from sklearn.ensemble import RandomForestClassifier
    from sklearn.datasets import load_iris
    from sklearn.model_selection import train_test_split
    from sklearn.metrics import accuracy_score, precision_score, recall_score, f1_score
    
    # Replace this with the ARN of the Tracking Server you just created
    arn = 'YOUR-TRACKING-SERVER-ARN'
    
    mlflow.set_tracking_uri(arn)
    
    # Load the Iris dataset
    iris = load_iris()
    X, y = iris.data, iris.target
    
    # Split the data into training and testing sets
    X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)
    
    # Train a Random Forest classifier
    rf_model = RandomForestClassifier(n_estimators=100, random_state=42)
    rf_model.fit(X_train, y_train)
    
    # Make predictions on the test set
    y_pred = rf_model.predict(X_test)
    
    # Calculate evaluation metrics
    accuracy = accuracy_score(y_test, y_pred)
    precision = precision_score(y_test, y_pred, average='weighted')
    recall = recall_score(y_test, y_pred, average='weighted')
    f1 = f1_score(y_test, y_pred, average='weighted')
    
    # Start an MLflow run
    with mlflow.start_run():
    # Log the model
    mlflow.sklearn.log_model(rf_model, "random_forest_model")
    
    # Log the evaluation metrics
    mlflow.log_metric("accuracy", accuracy)
    mlflow.log_metric("precision", precision)
    mlflow.log_metric("recall", recall)
    mlflow.log_metric("f1_score", f1)
  3. View your run in the MLflow UI
    Once you run the notebook shown in Step 2, you will see a new run in the MLflow UI.
  4. Compare runs
    You can run this notebook multiple times by changing the random_state to generate different metric values for each training run.

Register candidate models
Once you’ve compared the multiple runs as detailed in Step 4, you can register the model whose metrics best meet your requirements in the MLflow Model Registry. Registering a model indicates potential suitability for production deployment and there will be further testing to validate this suitability. Once a model is registered in MLflow it automatically appears in the SageMaker Model Registry for a unified model governance experience so you can deploy MLflow models to SageMaker inference. This enables data scientists who primarily use MLflow for experimentation to hand off their models to ML engineers who govern and manage production deployments of models using the SageMaker Model Registry.

Here is the model registered in the MLflow Model Registry.


Here is the model registered in the SageMaker Model Registry.

Clean up
Once created, an MLflow Tracking Server will incur costs until you delete or stop it. Billing for Tracking Servers is based on the duration the servers have been running, the size selected, and the amount of data logged to the Tracking Servers. You can stop Tracking Servers when they are not in use to save costs or delete them using API or the SageMaker Studio UI. For more details on pricing, see the Amazon SageMaker pricing.

Now available
SageMaker with MLflow is generally available in all AWS Regions where SageMaker Studio is available, except China and US GovCloud Regions. We invite you to explore this new capability and experience the enhanced efficiency and control it brings to your machine learning projects. To learn more, visit the SageMaker with MLflow product detail page.

For more information, visit the SageMaker Developer Guide and send feedback to AWS re:Post for SageMaker or through your usual AWS support contacts.

— Veliswa

AWS Weekly Roundup: Passkey MFA, Malware Protection on Amazon S3, and more (June 17, 2024)

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-passkey-mfa-malware-protection-on-amazon-s3-and-more-june-17-2024/

Last week, my alma mater Standard Bank Group (SBG) hosted a Software Engineering Conference and invited me to be one of the keynote speakers. SBG has presence throughout Africa and this hybrid conference was attended by almost 2,000 engineers from across the continent. It was amazing to reconnect with long-time friends and former colleagues, and to make new friends.

Last week’s launches
Here are some launches that got my attention during the previous week.

Passkey multi-factor authentication (MFA) for root and IAM users – We’ve added passkeys to the list of supported multi-factor authentication (MFA) for your root and AWS Identity and Access Management (IAM) users, to give you the convenience of use and easy recoverability. A passkey is a pair of cryptographic keys generated on your client device when you register for a service or a website. Passkeys can be used to replace passwords. However, for this initial release, we choose to use passkeys as a second factor authentication, in addition to your password.

Amazon GuardDuty Malware Protection for Amazon S3 – At AWS re:Inforce 2024 this past week, we announced general availability of Amazon GuardDuty Malware Protection for Amazon Simple Storage Service (Amazon S3). This is an expansion of GuardDuty Malware Protection to detect malicious file uploads to selected S3 buckets. Benefits include the ability to fully manage malware detection without managing compute infrastructure, and coverage summary for all protected buckets in your organization, to name a few. Read more in the post published last week detailing Amazon GuardDuty Malware Protection for Amazon S3.

IAM Access Analyzer Update – More goodness out of AWS re:Inforce 2024 last week! We announced an IAM Access Analyzer Update, which allows you to extend custom policy checks and also includes a guided revocation. This gives you guidance that you can share with your developers so that they can revoke unneeded permissions. My colleague Jeff Barr writes about it in more detail in this post.

Other AWS news
AWS open source news and updates – My colleague Ricardo writes this weekly open source newsletter in which he highlights new open source projects, tools, and demos from the AWS Community.

The .Net developer community remains close to our hearts here at AWS. I’m inspired by my colleagues Brandon Minnick and Francois Bouteruche who support this community, resulting in the AWS and the Azure engineering teams working together to create delightful .NET developer experiences. At the recently held NDC Oslo, which is part of the NDC Conferences hosted around the world, VP of Azure Developer Experience, Scott Hunter, talked about this collaboration during his keynote. Make sure to catch the keynote on the NDC Conferences YouTube Channel as soon as it’s published.

Upcoming AWS events
AWS Summits – These are free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Whether you’re in the Americas, Asia Pacific & Japan, or EMEA region, learn here about future AWS Summit events happening in your area.

AWS Community Days – Join an AWS Community Day event just like the one I mentioned at the beginning of this post to participate in technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from your area. If you’re in Sri Lanka, there’s an event happening in your area next week.

You can browse all upcoming in-person and virtual events here.

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Veliswa

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS.

In the Works – AWS Region in Taiwan

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/in-the-works-aws-region-in-taiwan/

Today, we’re announcing that a new AWS Region will be coming to Taiwan by early 2025. The new AWS Asia Pacific (Taipei) Region will consist of three Availability Zones at launch, and will give AWS customers in Taiwan the ability to run workloads and store data that must remain in Taiwan.

Each of the Availability Zones will be physically independent of the others in the Region – close enough to support applications that need low latency, yet sufficiently distant to significantly reduce the risk that an event at an Availability Zone level might impact business continuity.

The Availability Zones in this Region will be connected together through high-bandwidth, low-latency network connections over dedicated, fully redundant fiber. This connectivity supports applications that need synchronous replication between Availability Zones for availability or redundancy. You can take a peek at the AWS Global Infrastructure page to learn more about how we design and build Regions and Availability Zones.

We are currently working on Regions in Malaysia, Mexico, New Zealand, the Kingdom of Saudi Arabia, Thailand, and the AWS European Sovereign Cloud. The AWS Cloud operates 105 Availability Zones within 33 AWS Regions around the world, with announced plans for 21 more Availability Zones and seven more Regions, including Taiwan.

AWS in Taiwan
AWS has been investing and supporting customers and partners in Taiwan for more than 10 years. To support our customers in Taiwan, we have business development teams, solutions architects, partner managers, professional services consultants, support staff, and various other roles working in our Taipei office.

Other AWS infrastructure includes two Amazon CloudFront edge locations along with access to the AWS global backbone through multiple redundant submarine cables. You can access any other AWS Region (except Beijing and Ningxia) from AWS Direct Connect locations in Taipei, operated by Chief Telecom and Chunghwa Telecom. With AWS Direct Connect, your data that would have previously been transported over the internet is delivered through a private network connection between your facilities and AWS.

You can also use AWS Outposts in Taiwan, a family of fully managed solutions delivering AWS infrastructure and services to virtually any on-premises or edge location for a truly consistent hybrid experience. With AWS Local Zones in Taipei, you can deliver applications that require single-digit millisecond latency to end users.

AWS continues to invest in upskilling students, local developers and technical professionals, nontechnical professionals, and the next generation of IT leaders in Taiwan through offerings like AWS Academy, AWS Educate, and AWS Skill Builder. Since 2017, AWS has trained more than eight million people across the Asia Pacific-Japan region on cloud skills, including more than 100,000 people in Taiwan.

To learn more, join AWS Summit 2024 Taiwan in July; in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS.

AWS customers in Taiwan
AWS customers in Taiwan have been increasingly moving their applications to AWS and running their technology infrastructure in other AWS Regions around the world. With the addition of this new AWS Region, customers will be able to provide even lower latency to end users and use advanced technologies such as generative artificial intelligence (generative AI), Internet of Things (IoT), mobile services, and more, to drive innovation. This Region will give AWS customers the ability to run their workloads and store their content in Taiwan.

Here are some examples of customers using AWS to drive innovation:

Chunghwa Telecom is the largest integrated telecom provider in Taiwan. To improve AI data security and governance, they use Amazon Bedrock for a variety of generative AI applications, including automatically generating specifications documents for the software development lifecycle and crafting custom marketing campaigns. With Amazon Bedrock, Chunghwa Telecom is saving developer hours and has also developed an immersive, interactive virtual English teacher for the first time.

Gamania Group is a leader in the development and publication of online games in Taiwan. To maximize the value of running on AWS, they worked with AWS Training and Certification to enhance AWS skills across all of its departments, such as AWS Classroom training, AWS Well-Architected Framework, and AWS GameDay events. As a result, they reduced the time needed to make critical operational decisions by 50 percent, lowered its time-to-market by up to 70 percent, and accelerated the launch of new games.

KKCompany Technologies is a multimedia technology group building a music streaming platform, AI-powered streaming solution, and cloud intelligence service in Taiwan. The company specializes in generative AI, multimedia technology, and digital transformation consulting services for enterprises in Taiwan and Japan. You can find BlendVision, a cloud-based streaming solution in AWS Marketplace.

To learn more about Taiwan customer cases, visit AWS Customer Success Stories in English or our Traditional Chinese page.

Stay Tuned
We’ll announce the opening of this and the other Regions in future blog posts, so be sure to stay tuned! To learn more, visit the AWS Region in Taiwan page in Traditional Chinese.

— Channy

AWS Audit Manager extends generative AI best practices framework to Amazon SageMaker

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/aws-audit-manager-extends-generative-ai-best-practices-framework-to-amazon-sagemaker/

Sometimes I hear from tech leads that they would like to improve visibility and governance over their generative artificial intelligence applications. How do you monitor and govern the usage and generation of data to address issues regarding security, resilience, privacy, and accuracy or to validate against best practices of responsible AI, among other things? Beyond simply taking these into account during the implementation phase, how do you maintain long-term observability and carry out compliance checks throughout the software’s lifecycle?

Today, we are launching an update to the AWS Audit Manager generative AI best practice framework on AWS Audit Manager. This framework simplifies evidence collection and enables you to continually audit and monitor the compliance posture of your generative AI workloads through 110 standard controls which are pre-configured to implement best practice requirements. Some examples include gaining visibility into potential personally identifiable information (PII) data that may not have been anonymized before being used for training models, validating that multi-factor authentication (MFA) is enforced to gain access to any datasets used, and periodically testing backup versions of customized models to ensure they are reliable before a system outage, among many others. These controls perform their tasks by fetching compliance checks from AWS Config and AWS Security Hub, gathering user activity logs from AWS CloudTrail and capturing configuration data by making application programming interface (API) calls to relevant AWS services. You can also create your own custom controls if you need that level of flexibility.

Previously, the standard controls included with v1 were pre-configured to work with Amazon Bedrock and now, with this new version, Amazon SageMaker is also included as a data source so you may gain tighter control and visibility of your generative AI workloads on both Amazon Bedrock and Amazon SageMaker with less effort.

Enforcing best practices for generative AI workloads
The standard controls included in the “AWS generative AI best practices framework v2” are organized under domains named accuracy, fair, privacy, resilience, responsible, safe, secure and sustainable.

Controls may perform automated or manual checks or a mix of both. For example, there is a control which covers the enforcement of periodic reviews of a model’s accuracy over time. It automatically retrieves a list of relevant models by calling the Amazon Bedrock and SageMaker APIs, but then it requires manual evidence to be uploaded at certain times showing that a review has been conducted for each of them.

You can also customize the framework by including or excluding controls or customizing the pre-defined ones. This can be really helpful when you need to tailor the framework to meet regulations in different countries or update them as they change over time. You can even create your own controls from scratch though I would recommend you search the Audit Manager control library first for something that may be suitable or close enough to be used as a starting point as it could save you some time.

The Control library interface featuring a search box and three tabs: Common, Standard and Custom.

The control library where you can browse and search for common, standard and custom controls.

To get started you first need to create an assessment. Let’s walk through this process.

Step 1 – Assessment Details
Start by navigating to Audit Manager in the AWS Management Console and choose “Assessments”. Choose “Create assessment”; this takes you to the set up process.

Give your assessment a name. You can also add a description if you desire.

Step 1 screen of the assessment creation process. It has a textbox where you must enter a name for your assessment and a description text box where you can optionally enter a description.

Choose a name for this assessment and optionally add a description.

Next, pick an Amazon Simple Storage Service (S3) bucket where Audit Manager stores the assessment reports it generates. Note that you don’t have to select a bucket in the same AWS Region as the assessment, however, it is recommended since your assessment can collect up to 22,000 evidence items if you do so, whereas if you use a cross-Region bucket then that quota is significantly reduced to 3,500 items.

Interface with a textbox where you can type or search for your S3 buckets as well as buttons for browsing and creating a new bucket.

Choose the S3 bucket where AWS Audit Manager can store reports.

Next, we need to pick the framework we want to use. A framework effectively works as a template enabling all of its controls for use in your assessment.

In this case, we want to use the “AWS generative AI best practices framework v2” framework. Use the search box and click on the matched result that pops up to activate the filter.

The Framework searchbox where we typed "gene" which is enough to bring a few results with the top one being "AWS Generative AI Best Practices Framework v2"

Use the search box to find the “AWS generative AI best practices framework V2”

You then should see the framework’s card appear .You can choose the framework’s title, if you wish, to learn more about it and browse through all the included controls.

Select it by choosing the radio button in the card.

A widget containing the framework's title and summary with a radio button that has been checked.

Check the radio button to select the framework.

You now have an opportunity to tag your assessment. Like any other resources, I recommend you tag this with meaningful metadata so review Best Practices for Tagging AWS Resources if you need some guidance.

Step 2 – Specify AWS accounts in scope
This screen is quite straight-forward. Just pick the AWS accounts that you want to be continuously evaluated by the controls in your assessment. It displays the AWS account that you are currently using, by default. Audit Manager does support running assessments against multiple accounts and consolidating the report into one AWS account, however, you must explicitly enable integration with AWS Organizations first, if you would like to use that feature.

Screen displaying all the AWS accounts available for you to select that you want to include in your assessment.

Select the AWS accounts that you want to include in your assessment.

I select my own account as listed and choose “Next”

Step 3 – Specify audit owners
Now we just need to select IAM users who should have full permissions to use and manage this assessment. It’s as simple as it sounds. Pick from a list of identity and access management (IAM) users or roles available or search using the box. It’s recommended that you use the AWSAuditManagerAdministratorAccess policy.

You must select at least one, even if it’s yourself which is what I do here.

Interface for searching and selecting IAM users or roles.

Select IAM users or roles who will have full permissions over this assessment and act as owners.

Step 4 – Review and create
All that is left to do now is review your choices and click on “Create assessment” to complete the process.

Once the assessment is created, Audit Manager starts collecting evidence in the selected AWS accounts and you start generating reports as well as surfacing any non-compliant resources in the summary screen. Keep in mind that it may take up to 24 hours for the first evaluation to show up.

The summary screen for the assessment showing details such as how many controls are available, the status of each control displaying whether they "under review" or their compliance status plus tabs where you can revisit the assessment configuration.

You can visit the assessment details screen at any time to inspect the status for any of the controls.

Conclusion
The “AWS generative AI best practices framework v2” is available today in the AWS Audit Manager framework library in all AWS Regions where Amazon Bedrock and Amazon SageMaker are available.

You can check whether Audit Manager is available in your preferred Region by visiting AWS Services by Region.

If you want to dive deeper, check out a step-by-step guide on how to get started.

Simplify AWS CloudTrail log analysis with natural language query generation in CloudTrail Lake (preview)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/simplify-aws-cloudtrail-log-analysis-with-natural-language-query-generation-in-cloudtrail-lake-preview/

Today, I am happy to announce in preview the generative artificial intelligence (generative AI)–powered natural language query generation in AWS CloudTrail Lake, which is a managed data lake for capturing, storing, accessing, and analyzing AWS CloudTrail activity logs to meet compliance, security, and operational needs. You can ask a question using natural language about these activity logs (management and data events) stored in CloudTrail Lake without having the technical expertise to write a SQL query or spend time to decode the exact structure of activity events. For example, you might ask, “Tell me how many database instances are deleted without a snapshot”, and the feature will convert that question to a CloudTrail Lake query, which you can run as-is or modify to get the requested event information. Natural language query generation makes the process of exploration of AWS activity logs simpler.

Now, let me show you how to start using natural language query generation.

Getting started with natural language query generation
The natural language query generator uses generative AI to produce a ready-to-use SQL query from your prompt, which you can then choose to run in the query editor of CloudTrail Lake.

In the AWS CloudTrail console, I choose Query under Lake. The query generator can only generate queries for event data stores that collect CloudTrail management and data events. I choose an event data store for my CloudTrail Lake query from the dropdown list in Event data store. In the Query generator, I enter the following prompt in the Prompt field using natural language:

How many errors were logged during the past month?

Then, I choose Generate query. The following SQL query is automatically generated:

SELECT COUNT(*) AS error_count
FROM 8a6***
WHERE eventtime >= '2024-04-21 00:00:00'
    AND eventtime <= '2024-05-21 23:59:59'
    AND (
        errorcode IS NOT NULL
        OR errormessage IS NOT NULL
    )

I choose Run to see the results.

This is interesting, but I want to know more details. I want to see which services had the most errors and why these actions were erroring out. So I enter the following prompt to request additional details:

How many errors were logged during the past month for each service and what was the cause of each error?

I choose Generate query, and the following SQL query is generated:

SELECT eventsource,
    errorcode,
    errormessage,
    COUNT(*) AS errorCount
FROM 8a6***
WHERE eventtime >= '2024-04-21 00:00:00'
    AND eventtime <= '2024-05-21 23:59:59'
    AND (
        errorcode IS NOT NULL
        OR errormessage IS NOT NULL
    )
GROUP BY 1,
    2,
    3
ORDER BY 4 DESC;

I choose Run to see the results.

In the results, I see that my account experiences most number of errors related to Amazon S3, and top errors are related to CORS and object level configuration. I can continue to dig deeper to see more details by asking further questions. But now let me give natural language query generator another instruction. I enter the following prompt in the Prompt field:

What are the top 10 AWS services that I used in the past month? Include event name as well.

I choose Generate query, and the following SQL query is generated. This SQL statement retrieves the field names (eventSource,
eventName, COUNT(*) AS event_count), restricts the rows with the date interval of the past month in the WHERE clause, groups the rows by eventSource and eventName, sorts them by the usage count, and limit the result to 10 rows as I requested in a natural language.

SELECT eventSource,
    eventName,
    COUNT(*) AS event_count
FROM 8a6***
WHERE eventTime >= timestamp '2024-04-21 00:00:00'
    AND eventTime <= timestamp '2024-05-21 23:59:59'
GROUP BY 1,
    2
ORDER BY 3 DESC
LIMIT 10;

Again, I choose Run to see the results.

I now have a better understanding of how many errors were logged during the past month, what service the error was for, and what caused the error. You can try asking questions in plain language and run the generated queries over your logs to see how this feature works with your data.

Join the preview
Natural language query generation is available in preview in the US East (N. Virginia) Region as part of CloudTrail Lake.

You can use natural language query generation in preview for no additional cost. CloudTrail Lake query charges apply when running the query to generate results. For more information, visit AWS CloudTrail Pricing.

To learn more and get started using natural language query generation, visit AWS CloudTrail Lake User Guide.

— Esra

Introducing Amazon GuardDuty Malware Protection for Amazon S3

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/introducing-amazon-guardduty-malware-protection-for-amazon-s3/

Today we are announcing the general availability of Amazon GuardDuty Malware Protection for Amazon Simple Storage Service (Amazon S3), an expansion of GuardDuty Malware Protection to detect malicious file uploads to selected S3 buckets. Previously, GuardDuty Malware Protection provided agentless scanning capabilities to identify malicious files on Amazon Elastic Block Store (Amazon EBS) volumes attached to Amazon Elastic Compute Cloud (Amazon EC2) and container workloads.

Now, you can continuously evaluate new objects uploaded to S3 buckets for malware and take action to isolate or eliminate any malware found. Amazon GuardDuty Malware Protection uses multiple Amazon Web Services (AWS) developed and industry-leading third-party malware scanning engines to provide malware detection without degrading the scale, latency, and resiliency profile of Amazon S3.

With GuardDuty Malware Protection for Amazon S3, you can use built-in malware and antivirus protection on your designated S3 buckets to help you remove the operational complexity and cost overhead associated with automating malicious file evaluation at scale. Unlike many existing tools used for malware analysis, this managed solution from GuardDuty does not require you to manage your own isolated data pipelines or compute infrastructure in each AWS account and AWS Region where you want to perform malware analysis.

Your development and security teams can work together to configure and oversee malware protection throughout your organization for select buckets where new uploaded data from untrusted entities is required to be scanned for malware. You can configure post-scan action in GuardDuty, such as object tagging, to inform downstream processing, or consume the scan status information provided through Amazon EventBridge to implement isolation of malicious uploaded objects.

Getting started with GuardDuty Malware Protection for your S3 bucket
To get started, in the GuardDuty console, select Malware Protection for S3 and choose Enable.

Enter the S3 bucket name or choose Browse S3 to select an S3 bucket name from a list of buckets that belong to the currently selected Region. You can select All the objects in the S3 bucket when you want GuardDuty to scan all the newly uploaded objects in the selected bucket. Or you can also select Objects beginning with a specific prefix when you want to scan the newly uploaded objects that belong to a specific prefix.

After scanning a newly uploaded S3 object, GuardDuty can add a predefined tag with the key as GuardDutyMalwareScanStatus and the value as the scan status:

  • NO_THREATS_FOUND – No threat found in the scanned object.
  • THREATS_FOUND – Potential threat detected during scan.
  • UNSUPPORTED – GuardDuty cannot scan this object because of size.
  • ACCESS_DENIED – GuardDuty cannot access object. Check permissions.
  • FAILED – GuardDuty could not scan the object.

When you want GuardDuty to add tags to your scanned S3 objects, select Tag objects. If you use tags, you can create policies to prevent objects from being accessed before the malware scan completes and prevent your application from accessing malicious objects.

Now, you must first create and attach an AWS Identity and Access Management (IAM) role that includes the required permissions:

  • EventBridge actions to create and manage the EventBridge managed rule so that Malware Protection for S3 can listen to your S3 Event Notifications.
  • Amazon S3 and EventBridge actions to send S3 Event Notifications to EventBridge for all events in this bucket.
  • Amazon S3 actions to access the uploaded S3 object and add a predefined tag to the scanned S3 object.
  • AWS Key Management Service (AWS KMS) key actions to access the object before scanning and putting a test object on buckets with the supported DSSE-KMS and SSE-KMS

To add these permissions, choose View permissions and copy the policy template and trust relationship template. These templates include placeholder values that you should replace with the appropriate values associated with your bucket and AWS account. You should also replace the placeholder value for the AWS KMS key ID.

Now, choose Attach permissions, which opens the IAM console in a new tab. You can choose to create a new IAM role or update an existing IAM role with the permissions from the copied templates. If you want to create or update your IAM role in advance, visit Prerequisite – Create or update IAM PassRole policy in the AWS documentation.

Finally, go back to the GuardDuty browser tab that has the IAM console open, choose your created or updated IAM role, and choose Enable.

Now, you will see Active in the protection Status column for this protected bucket.

Choose View all S3 malware findings to see the generated GuardDuty findings associated with your scanned S3 bucket. If you see the finding type S3Object:S3/MaliciousFile, GuardDuty has detected the listed S3 object as malicious. Choose the Threats detected section in the Findings details panel and follow the recommended remediation steps. To learn more, visit Remediating a potentially malicious S3 object in the AWS documentation.

Things to know
You can set up GuardDuty Malware Protection for your S3 buckets even without GuardDuty enabled for your AWS account. However, if you enable GuardDuty in your account, you can use the full monitoring of foundational sources, such as AWS CloudTrail management events, Amazon Virtual Private Cloud (Amazon VPC) Flow Logs, and DNS query logs, as well as malware protection features. You can also have security findings sent to AWS Security Hub and Amazon Detective for further investigation.

GuardDuty can scan files belonging to the following synchronous Amazon S3 storage classes: S3 Standard, S3 Intelligent-Tiering, S3 Standard-IA, S3 One Zone-IA, and Amazon S3 Glacier Instant Retrieval. It will scan the file formats known to be used to spread or contain malware. At the launch, the feature supports file sizes up to 5 GB, including archive files with up to five levels and 1,000 files per level after it is decompressed.

As I said, GuardDuty will send scan metrics to your EventBridge for each protected S3 bucket. You can set up alarms and define post-scan actions, such as tagging the object or moving the malicious object to a quarantine bucket. To learn more about other monitoring options, such as Amazon CloudWatch metrics and S3 object tagging, visit Monitoring S3 object scan status in the AWS documentation.

Now available
Amazon GuardDuty Malware Protection for Amazon S3 is generally available today in all AWS Regions where GuardDuty is available, excluding China Regions and GovCloud (US) Regions.

The pricing is based on the GB volume of the objects scanned and number of objects evaluated per month. This feature comes with a limited AWS Free Tier, which includes 1,000 requests and 1 GB each month, pursuant to conditions for the first 12 months of account creation for new AWS accounts, or until June 11, 2025, for existing AWS accounts. To learn more, visit the Amazon GuardDuty pricing page.

Give GuardDuty Malware Protection for Amazon S3 a try in the GuardDuty console. For more information, visit the Amazon GuardDuty User Guide and send feedback to AWS re:Post for Amazon GuardDuty or through your usual AWS support contacts.

— Channy

IAM Access Analyzer Update: Extending custom policy checks & guided revocation

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/iam-access-analyzer-update-extending-custom-policy-checks-guided-revocation/

We are making IAM Access Analyzer even more powerful, extending custom policy checks and adding easy access to guidance that will help you to fine-tune your IAM policies. Both of these new features build on the Custom Policy Checks and the Unused Access analysis that were launched at re:Invent 2023. Here’s what we are launching:

New Custom Policy Checks – Using the power of automated reasoning, the new checks help you to detect policies that grant access to specific, critical AWS resources, or that grant any type of public access. Both of the checks are designed to be used ahead of deployment, possibly as part of your CI/CD pipeline, and will help you proactively detect updates that do not conform to your organization’s security practices and policies.

Guided Revocation – IAM Access Analyzer now gives you guidance that you can share with your developers so that they can revoke permissions that grant access that is not actually needed. This includes unused roles, roles with unused permissions, unused access keys for IAM users, and unused passwords for IAM users. The guidance includes the steps needed to either remove the extra items or to replace them with more restrictive ones.

New Custom Policy Checks
The new policy checks can be invoked from the command line or by calling an API function. The checks examine a policy document that is supplied as part of the request and return a PASS or FAIL value. In both cases, PASS indicates that the policy document properly disallows the given access, and FAIL indicates that the policy might allow some or all of the permissions. Here are the new checks:

Check No Public Access – This check operates on a resource policy, and checks to see if the policy grants public access to a specified resource type. For example, you can check a policy to see if it allows public access to an S3 bucket by specifying the AWS::S3::Bucket resource type. Valid resource types include DynamoDB tables and streams, EFS file systems, OpenSearch domains, Kinesis streams and stream consumers, KMS keys, Lambda functions, S3 buckets and access points, S3 Express directory buckets, S3 Outposts buckets and access points, Glacier, Secrets Manager secrets, SNS topics and queues, and IAM policy documents that assume roles. The list of valid resource types will expand over time and can be found in the CheckNoPublicAccess documentation,

Let’s say that I have a policy which accidentally grants public access to an Amazon Simple Queue Service (Amazon SQS) queue. Here’s how I check it:

$ aws accessanalyzer check-no-public-access --policy-document file://resource.json \
  --resource-type AWS::SQS::Queue --output json

And here is the result:

{
    "result": "FAIL",
    "message": "The resource policy grants public access for the given resource type.",
    "reasons": [
        {
            "description": "Public access granted in the following statement with sid: SqsResourcePolicy.",
            "statementIndex": 0,
            "statementId": "SqsResourcePolicy"
        }
    ]
}

I edit the policy to remove the access grant and try again, and this time the check passes:

{
    "result": "PASS",
    "message": "The resource policy does not grant public access for the given resource type."
}

Check Access Not Granted – This check operates on a single resource policy or identity policy at a time. It also accepts an list of actions and resources, both in the form that are acceptable as part of an IAM policy. The check sees if the policy grants unintended access to any of the resources in the list by way of the listed actions. For example, this check could be used to make sure that a policy does not allow a critical CloudTrail trail to be deleted:

$ aws accessanalyzer check-access-not-granted --policy-document file://ct.json \
  --access resources="arn:aws:cloudtrail:us-east-1:123456789012:trail/MySensitiveTrail" \
  --policy-type IDENTITY_POLICY --output json

IAM Access Analyzer indicates that the check fails:

{
    "result": "FAIL",
    "message": "The policy document grants access to perform one or more of the listed actions or resources.",
    "reasons": [
        {
            "description": "One or more of the listed actions or resources in the statement with index: 0.",
            "statementIndex": 0
        }
    ]
}

I fix the policy and try again, and this time the check passes, indicating that the policy does not grant access to the listed resources:

{
    "result": "PASS",
    "message": "The policy document does not grant access to perform the listed actions or resources."
}

Guided Revocation
In my earlier post I showed you how IAM Access Analyzer discovers and lists IAM items that grant access which is not actually needed. With today’s launch, you now get guidance to help you (or your developer team) to resolve these findings. Here are the latest findings from my AWS account:

Some of these are leftovers from times when I was given early access to a service so that I could use and then blog about it; others are due to my general ineptness as a cloud admin! Either way, I need to clean these up. Let’s start with the second one, Unused access key. I click on the item and can see the new Recommendations section at the bottom:

I can follow the steps and delete the access key or I can click Archive to remove the finding from the list of active findings and add it to the list of archived ones. I can also create an archive rule that will do the same for similar findings in the future. Similar recommendations are provided for unused IAM users, IAM roles, and passwords.

Now let’s take a look at a finding of Unused permissions:

The recommendation is to replace the existing policy with a new one. I can preview the new policy side-by-side with the existing one:

As in the first example I can follow the steps or I can archive the finding.

The findings and the recommendations are also available from the command line. I generate the recommendation by specifying an analyzer and a finding from it:

$ aws accessanalyzer generate-finding-recommendation \
  --analyzer-arn arn:aws:access-analyzer-beta:us-west-2:123456789012:analyzer/MyAnalyzer \
  --id 67110f3e-05a1-4562-b6c2-4b009e67c38e

Then I retrieve the recommendation. In this example, I am filtering the output to only show the steps since the entire JSON output is fairly rich:

$ aws accessanalyzer get-finding-recommendation \
  --analyzer-arn arn:aws:access-analyzer-beta:us-west-2:123456789012:analyzer/MyAnalyzer \
  --id 67110f3e-05a1-4562-b6c2-4b009e67c38e --output json | \
  jq .recommendedSteps[].unusedPermissionsRecommendedStep.recommendedAction
"CREATE_POLICY"
"DETACH_POLICY"

You can use these commands (or the equivalent API calls) to integrate the recommendations into your own tools and systems.

Available Now
The new checks and the resolution steps are available now and you can start using them today in all public AWS regions!

— Jeff;

AWS adds passkey multi-factor authentication (MFA) for root and IAM users

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-adds-passkey-multi-factor-authentication-mfa-for-root-and-iam-users/

Security is our top priority at Amazon Web Services (AWS), and today, we’re launching two capabilities to help you strengthen the security posture of your AWS accounts:

MFA is one of the simplest and most effective ways to enhance account security, offering an additional layer of protection to help prevent unauthorized individuals from gaining access to systems or data.

MFA with passkey for your root and IAM users
Passkey is a general term used for the credentials created for FIDO2 authentication.

A passkey is a pair of cryptographic keys generated on your client device when you register for a service or a website. The key pair is bound to the web service domain and unique for each one.

The public part of the key is sent to the service and stored on their end. The private part of the key is either stored in a secured device, such as a security key, or securely shared across your devices connected to your user account when you use cloud services, such as iCloud Keychain, Google accounts, or a password manager such as 1Password.

Typically, the access to the private part of the key is protected by a PIN code or a biometric authentication, such as Apple Face ID or Touch ID or Microsoft Hello, depending on your devices.

When I try to authenticate on a service protected with passkeys, the service sends a challenge to my browser. The browser then requests my device sign the challenge with my private key. This triggers a PIN or biometric authentication to access the secured storage where the private key is stored. The browser returns the signature to the service. When the signature is valid, it confirms I own the private key that matches the public key stored on the service, and the authentication succeeds.

You can read more about this process and the various standards at work (FIDO2, CTAP, WebAuthn) in the post I wrote when AWS launched support for passkeys in AWS IAM Identity Center back in November 2020.

Passkeys can be used to replace passwords. However, for this initial release, we choose to use passkeys as a second factor authentication, in addition to your password. The password is something you know, and the passkey is something you have.

Passkeys are more resistant to phishing attacks than passwords. First, it’s much harder to gain access to a private key protected by your fingerprint, face, or a PIN code. Second, passkeys are bound to a specific web domain, reducing the scope in case of unintentional disclosure.

As an end user, you will benefit from the convenience of use and easy recoverability. You can use the built-in authenticators in your phones and laptops to unlock a cryptographically secured credential to your AWS sign-in experience. And when using a cloud service to store the passkey (such as iCloud keychain, Google accounts, or 1Password), the passkey can be accessed from any of your devices connected to your passkey provider account. This helps you to recover your passkey in the unfortunate case of losing a device.

How to enable passkey MFA for an IAM user
To enable passkey MFA, I navigate to the AWS Identity and Access Management (IAM) section of the console. I select a user, and I scroll down the page to the Multi-factor authentication (MFA) section. Then, I select Assign MFA device.

Note that to help you increase resilience and account recovery, you can have multiple MFA devices enabled for a user.

Enable MFA in AM console

On the next page, I enter an MFA device name, and I select Passkey or security key. Then, I select next.

enable MFA : select passkey

When using a password manager application that supports passkeys, it will pop up and ask if you want to generate and store a passkey using that application. Otherwise, your browser will present you with a couple of options. The exact layout of the screen depends on the operating system (macOS or Windows) and the browser you use. Here is the screen I see on macOS with a Chromium-based browser.

Enable passkey : choose method

The rest of the experience depends on your selection. iCloud Keychain will prompt you for a Touch ID to generate and store the passkey.

In the context of this demo, I want to show you how to bootstrap the passkey on another device, such as a phone. I therefore select Use a phone, tablet, or security key instead. The browser presents me with a QR code. Then, I use my phone to scan the QR code. The phone authenticates me with Face ID and generates and stores the passkey.

Passkey : scan a QR code

This QR code-based flow allows a passkey from one device to be used to sign in on another device (a phone and my laptop in my demo). It is defined by the FIDO specification and known as cross device authentication (CDA).

When everything goes well, the passkey is now registered with the IAM user.

Enable passkey : success

Note that we don’t recommend using IAM users to authenticate human beings to the AWS console. We recommend configuring single sign-on (SSO) with AWS IAM Identity Center instead.

What’s the sign-in experience?
Once MFA is enabled and configured with a passkey, I try to sign in to my account.

The user experience differs based on the operating system, browser, and device you use.

For example, on macOS with iCloud Keychain enabled, the system prompts me for a touch on the Touch ID key. For this demo, I registered the passkey on my phone using CDA. Therefore, the system asks me to scan a QR code with my phone. Once scanned, the phone authenticates me with Face ID to unlock the passkey, and the AWS console terminates the sign-in procedure.

Authenticate with MFA and passkey

Enforcing MFA for root users
The second announcement today is that we have started to enforce the use of MFA for the root user on some AWS accounts. This change was announced last year in a blog post from Stephen Schmidt, Chief Security Officer at Amazon.

To quote Stephen:

Verifying that the most privileged users in AWS are protected with MFA is just the latest step in our commitment to continuously enhance the security posture of AWS customers.

We started with your most sensitive account: your management account for AWS Organizations. The deployment of the policy is progressive, with just a few thousand accounts at a time. Over the coming months, we will progressively deploy the MFA enforcement policy on root users for the majority of the AWS accounts.

When you don’t have MFA enabled on your root user account, and your account is updated, a new message will pop up when you sign in, asking you to enable MFA. You will have a grace period, after which the MFA becomes mandatory.

Enable MFA on root account

You can start to use passkeys for multi-factor authentication today in all AWS Regions, except in China.

We’re enforcing the use of multi-factor authentication in all AWS Regions, except for the two regions in China (Beijing, Ningxia) and for AWS GovCloud (US), because the AWS accounts in these Regions have no root user.

Now go activate passkey MFA for your root user in your accounts.

— seb

Lower Your Risk of SMS Fraud with Country Level Blocking and Amazon Pinpoint

Post Syndicated from Brett Ezell original https://aws.amazon.com/blogs/messaging-and-targeting/lower-your-risk-of-sms-fraud-with-country-level-blocking-and-amazon-pinpoint/

As a developer, marketing professional, or someone in the communications space, you’re likely familiar with the importance of SMS messaging in engaging customers and driving valuable interactions. However, you may have also encountered the growing challenge of artificially inflated traffic (AIT), also known as SMS pumping. A new report co-authored by
Enea revealed that AIT is so widespread within the SMS ecosystem that 19.8B-35.7B fraudulent messages were sent by bad actors in 2023, incurring substantial costs of over $1 billion. In this blog post, we’ll explore how you can use
Protect configurations, a powerful set of capabilities within
Amazon Pinpoint SMS, that provides granular control over which destination countries your SMS, MMS, and voice messages can be sent to.
<img decoding=” width=”1252″ height=”889″>

What is SMS Pumping, aka Artificially Inflated Traffic (AIT)?

AIT, or SMS pumping, is a type of fraud where bad actors use bots to generate large volumes of fake SMS traffic. These bots target businesses’ whose websites, apps, and other assets have forms or other mechanisms that trigger SMS being sent out. Common use cases for SMS such as one-time passwords (OTPs), app download links, promotion signups, etc. are all targets for these bad actors to “pump” SMS and send out fraudulent messages. The goal is to artificially inflate the number of SMS messages a business sends, resulting in increased costs and a negative impact on the sender’s reputation. In the realm of SMS-based artificially inflated traffic (AIT), the prevalent method for bad actors to profit involves colluding with parties in the SMS delivery chain to receive a portion of the revenue generated from each fraudulent message sent.

<img decoding=” width=”1280″ height=”720″>

AIT poses several challenges for businesses:

  1. Overspending: The fake SMS traffic generated by AIT bots results in businesses paying for messages that yield no actual results.

  2. Interrupted service: Large volumes of AIT can force businesses to temporarily halt SMS services, disrupting legitimate customer communications.

  3. Diverted focus: Dealing with AIT can shift businesses’ attention away from core operations and priorities.

  4. Reduced deliverability rates due to the messages never being interacted with and/or large volumes of SMS being sent quickly.

How does Protect mitigate AIT?

Amazon Pinpoint’s Protect feature allows you to control which countries you can send messages to. This is beneficial if your customers are located in specific countries.

With Protect, you can create a list of country rules that either allow or block messages to each destination country. These country rules can be applied to SMS, MMS, and voice messages sent from your AWS account. The Protect configurations you create enable precise control over which destination countries your messages can be sent to. This helps mitigate the impact of AIT by allowing you to tailor where you do or do not send.

Protect offers flexibility in how the country rules are applied. You can apply them at the account level, the configuration set level, or the individual message level. This enables you to customize your AIT mitigation strategy to best fit your business needs and messaging patterns.

By leveraging Protect within Amazon Pinpoint, you can help ensure the integrity and cost-effectiveness of your SMS, MMS, and voice communications.

Account-level Protect Configuration

The simplest approach is to create a Protect configuration and associate it as the account default. This means the allow/block rules defined in that configuration will be applied across all messages sent from your account, unless overridden. This is an effective option if you only need one set of country rules applied universally.

Configuration set-specific Protect configuration

You can associate a Protect configuration with one or more of your Pinpoint SMS configuration sets. This allows you to apply different country rules to distinct messaging flows or use cases within your application without changing your existing code if you are already using Config Sets. It also enables more detailed logging and monitoring of the Protect configuration’s impact, such as:

  1. Error Logs: Logging of any errors or issues encountered when messages are sent, providing insights into how the Protect configuration is affecting message delivery.
  2. Audit Logs: Records of all configuration changes, access attempts, and other relevant activities related to the Protect configuration, allowing for comprehensive auditing and monitoring.
  3. Usage Metrics: Tracking of usage statistics, such as the number of messages sent to different countries, the impact of the Protect configuration on message volumes, and other usage-related data.
  4. Compliance and Policy Enforcement Logs: Documentation of how the Protect configuration is enforcing compliance with messaging policies and regulations, including any instances where messages are blocked or allowed based on the configuration rules.

Dynamic Protect configuration per message

If your needs are even more specific, you can create a Protect configuration without any association, and then specify its ID when sending messages via the Pinpoint APIs (e.g. SendMediaMessage, SendTextMessage, SendVoiceMessage). This gives you the ability to dynamically choose the Protect configuration to apply for each individual message, providing the ultimate flexibility.

Regardless of the approach, the core benefit of Protect configurations is the ability to precisely control which destination countries your messages may be sent to. Blocking countries where you don’t have a presence or where SMS pricing is high eliminates your exposure to fraudulent AIT traffic originating from those regions. This helps protect your messaging budget, maintain service continuity, and focus your efforts on legitimate customer interactions.

Who should use Protect configurations?

Protect configurations are designed to benefit a wide range of AWS customers, particularly those who:

  1. Send SMS messages to a limited number of countries: If your business primarily operates in a few specific countries, Protect configurations can help you easily block SMS messages to countries where you don’t have a presence, reducing the risk of AIT.
  2. Have experienced AIT issues in the past: If your business has been a target of SMS pumping, Protect configurations can help you regain control over your SMS communications and prevent future AIT attacks.
  3. Want to proactively protect their SMS messaging: Even if you haven’t encountered AIT issues yet, Protect configurations can help you stay ahead of the curve and maintain the integrity of your SMS communications.

How to create a country rules list with Protect configuration

To begin building a list of country rules that allow or block messages to specific destination countries, you start by creating a new Protect configuration. There are two ways to accomplish this, either by using the console, or the API.

Option 1 – Using the AWS Console

Console Scenario: My account is out of the sandbox and I only want to send to 1 country – United Kingdom (iso:GB) using the SenderID “DEMOTP”.

At a high level, we will follow the three steps outlined below for each method. In our examples, we used a SenderID as our Originator. However, it should be noted that the same process can be achieved using any originator you’d like. i.e. SenderID, Phone pool, Phone number, 10DLC, short code, etc.

  1. Create SenderID (Optional if you already have one)
  2. Create Protect Configuration
  3. Send Test Message via console

Using the AWS Console

1) Create SenderID for United Kingdom (GB)

  • Pinpoint SMS Console – Request Originator
    • Select United Kingdom (GB) and follow the prompts for a SenderID. DO NOT select Two-way SMS Messaging
    • Enter Sender ID – Example: DEMOTP
    • Confirm and Request

2) Create default Protect Configuration

<img decoding=” width=”863″ height=”521″>

    • Search for Country=United Kingdom then deselect United Kingdom

<img decoding=” width=”865″ height=”582″>

    • Set as Account Default and select Create protect configuration

<img decoding=” width=”1497″ height=”1173″>

3) Send a test message with SMS simulator

Note: The Pinpoint SMS Simulator provides special phone numbers you can use to send test text messages and receive realistic event records, all within the confines of the Amazon Pinpoint service. These simulator phone numbers are designed to stay entirely within the Pinpoint SMS ecosystem, ensuring your test messages don’t get sent over the carrier network.

You can use these simulator phone numbers to send both SMS and MMS messages, allowing you to thoroughly validate your message content, workflow, and event handling. The responses you receive back will mimic either success or fail depending on which destination simulator number you send to.

  • From the Pinpoint SMS Console SMS Simulator page,
    • For Originator, Choose Sender ID, and select your Sender ID created from earlier.
    • Under Destination number, select Simulator numbers and choose United Kingdom (GB). Enter a test message in the Message body.
    • Finally, choose send test message. This should prompt a green “Success” banner at the top of your page.

<img decoding=” width=”1336″ height=”1313″>

    • Conversely, follow the previous test message steps, and instead attempt to send to anywhere other than the United Kingdom (GB). In this example, Australia (AU) 
    • As shown below in the screenshot this one is blocked since you have configured to only send to GB.

<img decoding=” width=”1333″ height=”1364″>

Option 2 – Using the V2 API and CLI

V2 API Scenario: 
My account is out of the sandbox and I want to BLOCK only 1 country – Australia (AU) while using the SenderID “DEMOTP”.

1) Create SenderID for GB

Note: before using the CLI remember to configure your access and secret key using

aws configure

Windows users should use PowerShell over cmd to test

  • Use RequestSenderId to create the same Sender Id as previously made via the console.
aws pinpoint-sms-voice-v2 request-sender-id --iso-country-code "GB" --sender-id "DEMOTP"

Response:

{
   "DeletionProtectionEnabled": False,
   "IsoCountryCode": "GB",
   "MessageTypes": [ "TRANSACTIONAL" ],
   "MonthlyLeasingPrice": "0.00",
   "Registered": False,
   "SenderId": "DEMOTP",
   "SenderIdArn": "string"
}

2) Create default Protect Configuration

aws pinpoint-sms-voice-v2 create-protect-configuration --tags Key=Name,Value=CLITESTING

Response:

{
   "AccountDefault": False,
   "CreatedTimestamp": number,
   "DeletionProtectionEnabled": False,
   "ProtectConfigurationArn": "string",
   "ProtectConfigurationId":  "string",
   "Tags": [ 
      { 
         "Key": "Name",
         "Value": "CLITESTING"
      }
   ]
}

  • Add AU as BLOCKED on protect configuration.
aws pinpoint-sms-voice-v2 update-protect-configuration-country-rule-set --protect-configuration-id protect-string --number-capability 'SMS' --country-rule-set-updates '{\"AU\":{\"ProtectStatus\":\"BLOCK\"}}'

Response:

{
   "CountryRuleSet": { 
      "string" : { 
         "ProtectStatus": "ALLOW | BLOCK"
      }
   },
   "NumberCapability": "SMS",
   "ProtectConfigurationArn": "string",
   "ProtectConfigurationId": "string"
}

  • Set as account default configuration.
aws pinpoint-sms-voice-v2 set-account-default-protect-configuration --protect-configuration-id protect-string

Response:

{
   "DefaultProtectConfigurationArn": "string",
   "DefaultProtectConfigurationId": "string"
}

3) Send test message

  • Use SendTextMessage to test your Protect Configuration via the V2 API.
  • Test sending to GB Simulator Number should be successful.
aws pinpoint-sms-voice-v2 send-text-message --destination-phone-number "string" --message-body "string"

Response:

{
   "MessageId": "string"
}

  • Test sending to AU Simulator Number should be blocked.
aws pinpoint-sms-voice-v2 send-text-message --destination-phone-number "string" --message-body "string"

Response – (ConflictException):

{
An error occurred (ConflictException) when calling the 
SendTextMessage operation: Conflict Occurred - 
Reason="DESTINATION_COUNTRY_BLOCKED_BY_PROTECT_CONFIGURATION" ResourceType="protect-configuration" ResourceId="string"
}

Conclusion

As SMS messaging continues to play a crucial role in customer engagement and authentication, protecting your communications from AIT is more important than ever. Amazon Pinpoint Protect provides a powerful and user-friendly solution to help you mitigate the impact of SMS pumping, ensuring the integrity of your SMS channels and preserving your business’ reputation and resources. Whether you’re a small business or a large enterprise, Pinpoint Protect is a valuable tool to have in your arsenal as you navigate the evolving landscape of SMS messaging.

To get started with Pinpoint SMS Protect, visit the Amazon Pinpoint SMS documentation or reach out to your AWS account team. And don’t forget to let us know in the comments how Protect configurations has helped you combat AIT and strengthen your SMS communications.

A few resources to help you plan for your SMS program:

About the Author

Brett Ezell

Brett Ezell is your friendly neighborhood Solutions Architect at AWS, where he specializes in helping customers optimize their SMS and email campaigns using Amazon Pinpoint and Amazon Simple Email Service. As a former US Navy veteran, Brett brings a unique perspective to his work, ensuring customers receive tailored solutions to meet their needs. In his free time, Brett enjoys live music, collecting vinyl, and the challenges of a good workout. And, as a self-proclaimed comic book aficionado, he can often be found combing through his local shop for new books to add to his collection.