Tag Archives: Security, Identity & Compliance

Fast Track ISM-ready cloud environments and IRAP Assessments with Landing Zone Accelerator on AWS

Post Syndicated from Kevin Donohue original https://aws.amazon.com/blogs/security/fast-track-ism-ready-cloud-environments-and-irap-assessments-with-landing-zone-accelerator-on-aws/

This post announces the availability of a new independent assessment report available on AWS Artifact analyzing how Landing Zone Accelerator on AWS (LZA) can automatically deploy multi-account environments in Amazon Web Services (AWS) with Australian Government Information Security Manual (ISM) security controls coverage at scale. The report includes findings from an independent third-party analysis conducted by AWS Partner gwi.digital. In addition to the report, we talk about ISM compliance applicability to LZA and a new testing mechanism for measuring configuration drift, which together can provide Australian customers with a documented and validated foundation to accelerate IRAP assessment readiness.

Background

Australian organizations in public sector, defense, and critical infrastructure agencies must build cloud environments that meet (ISM requirements. The ISM defines 1,081 security control requirements across 22 guideline chapters. Demonstrating compliance is central to achieving an IRAP assessment outcome, but assessments typically require months of preparation, evidence gathering, and testing.

In October 2025, we introduced the LZA Universal Configuration and LZA Compliance Workbook. LZA provisions a multi-account security architecture that automates the deployment of nearly 200 security controls based on AWS Well-Architected pillars and AWS security best practices. The LZA Compliance Workbook, available on AWS Artifact, documents how the Universal Configuration (UC) maps to technical security requirements from 17 global compliance frameworks, with more being added. LZA is an ideal solution for customers with security and compliance obligations—both existing and anticipated—because the guardrails it deploys are applied automatically to new accounts as environments grow.

What’s in the report

To see how LZA can help customers in Australia we teamed up with AWS Partner gwi.digital to run LZA as a customer would. gwi.digital is a consultancy partner specializing in cybersecurity and governance, risk, and compliance (GRC) and has deep experience in IRAP assessments and the ISM framework. The team conducted an independent analysis and evaluation of LZA UC against 1,081 ISM controls. The assessment was conducted in a greenfield AWS environment hosted in the ap-southeast-2 (Sydney) AWS Region, positioned within Phase 2 of the ASD Cloud Security Assessment and Authorization Framework and focused on cloud consumers building on already-authorized AWS services. It builds on existing AWS IRAP foundations: Underlying AWS services were most recently independently assessed at the PROTECTED level by CyberCX last year. While this report does not constitute an official IRAP authorization, certification, or accreditation, it provides a professional evaluation of evidence based on what LZA delivers out of the box (and what it does not), so organizations can make informed decisions.

What the assessment found

Of the 1,081 ISM controls, 256 are within the addressable scope of LZA and include the technical infrastructure controls that a solution like LZA can meaningfully address. Of those 256, LZA achieves Full or Partial coverage for 234 (91%). The remaining 825 controls are outside the scope of LZA: physical security, personnel, organizational governance, and classification-level exclusions. A key contribution for the assessment was analysis of the shared responsibility model that goes beyond the traditional AWS/customer binary. It considers a three-tier view—AWS (provided), LZA (enabled), and Customer (responsibility)—and further categorizes the 825 out-of-scope controls into subcategories so customers can quickly determine which controls require their attention compared to which are already addressed at the infrastructure level. By combining automated deployment, ISM-specific compliance mappings, independent validation, and continuous evidence generation, Australian customers can reduce IRAP assessment timelines while achieving more reliable compliance outcomes.

Note: Results are based on the configuration as-provisioned based on the LZA version and during the time of this assessment. Results may vary depending on customer implementation and configuration choices.

Continuous validation with CATS

Confirming controls are implemented and operating effectively across your environment is complex and often lacks complete coverage. To simplify testing your LZA deployment, we developed the Controls Acceptance Testing Suite (CATS). CATS is an automated compliance validation engine that runs purpose-built tests against the security configuration baseline deployed by LZA UC. For the ISM assessment, CATS executed over 3,600 individual tests across six AWS accounts, evaluating account structure, identity and access, network configuration, logging, encryption, and backup. For Australian customers, CATS enables:

  • Automated evidence generation: Machine-readable results may replace weeks of manual evidence collection
  • ISM-enriched reporting: gwi-digital developed a conversion script that maps CATS output to ISM control references, enabling auditors to interpret results from an ISM perspective
  • OSCAL export: Results in Open Security Controls Assessment Language (OSCAL) format for interoperability with assessment tools
  • Continuous drift detection: Repeatable execution identifies when configurations deviate from the validated baseline between assessment cycles

Note: CATS availability is limited and currently accessible only through AWS Professional Services as a private beta solution and may be subject to change. Availability, features, and pricing are subject to change without notice. Contact your AWS account representative or reach out to a member of the LZA team for questions about CATS, or to provide feedback on the LZA ISM report.

ISM-optimized configuration

Through the assessment, gwi-digital identified configuration adjustments that elevate specific control ratings from Partial to Full, with minimal effort; for example, increasing the default password length from 14 to 15 characters or adjusting log retention to align with Australian Federal Disposal Authority standards. These recommendations have been communicated to the LZA UC team for inclusion in a future ISM-specific guidance section in LZA GitHub documentation.

Getting started

In addition to the LZA ISM report, you can also find the LZA Compliance Workbook available on AWS Artifact. It maps related ISM requirement identifiers to security implementation statements, giving you a starting point from which you can customize and enhance your compliance documentation for your unique use cases after deploying LZA.

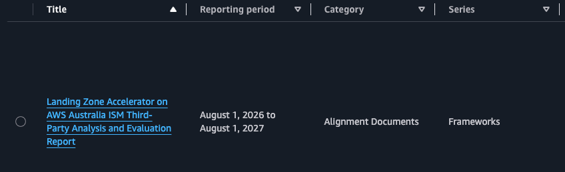
  1. Sign in to your AWS account and then download the LZA Australia ISM Third-Party Analysis and Evaluation Report and LZA Compliance Workbook from AWS Artifact.
    Figure 1: LZA report and workbook in AWS Artifact

    Figure 1: LZA report and workbook in AWS Artifact

  2. Visit the LZA Universal Configuration GitHub repository to review and download the latest configuration baseline.
  3. Use the LZA Implementation Guide to see use cases, review pre-deployment considerations and then follow deployment steps.
  4. Set-up a security compliance chat agent. Consider creating a knowledge base with Amazon Bedrock using the LZA Compliance Workbook, LZA Implementation Guide, web crawlers to the LZA GitHub, and your custom resources to set up your own chat agent.
If you have questions, contact a gwi.digitalexpert, AWS LZA team member, or your AWS account representative.

Conclusion

The combination of ISM mappings in the LZA Compliance Workbook, the gwi-digital analysis report, and CATS evidence gives Australian customers a head start on IRAP assessments.

  • Weeks saved on scoping: Pre-determined control applicability significantly reduces upfront scoping effort
  • Documentation ready: Implementation statements and control requirement alignment reduce the documentation burden
  • Independent assurance: A third-party report that customers and their assessors can reference directly
  • Continuous evidence: CATS generates repeatable security evidence between assessment cycles, replacing periodic manual audits with ongoing assurance

Acknowledgements

The Landing Zone Accelerator team would like to thank Baden Hughes, Henrik Melkonyan, Iain Lindsay-German, and Ian Roderick from gwi.digital for their professionalism and expertise in performing an incredibly thorough assessment, helping us to make LZA better for customers, and for their contributions to this blog post.

If you have feedback about this post, submit comments in the Comments section below.

Kevin Donohue

Kevin Donohue

Kevin is a Senior Security Compliance Engineer at AWS, where he builds solutions and resources to help AWS customers achieve their security and compliance goals. Prior to joining the Landing Zone Accelerator team in AWS Professional Services in 2024, Kevin began his tenure with AWS Security in 2019 specializing in FedRAMP compliance and the shared responsibility model.

Dan Friebe

Dan Friebe

Dan is a Senior Solutions Architect at AWS, helping customers design and build secure cloud solutions. With over a decade of AWS experience and 16+ years supporting public sector missions, he has spent 8 years delivering solutions for customers and enabling partners to deliver at scale. He’s passionate about removing friction between compliance and innovation, helping customers move faster without compromising security.

Dave Connell

Dave Connell

Dave Connell is a Senior Systems Development Engineer within AWS Professional Services. He has spent the last 7 years building software to secure and scale AWS usage, enabling builders to delight customers and deliver business value through excellent software in the cloud. Dave is passionate about enabling delivery of predictable, safe and valuable customer outcomes by empowering the builder.

AWS Network Firewall now supports rule hit count

Post Syndicated from Preetkumar Shah original https://aws.amazon.com/blogs/security/aws-network-firewall-now-supports-rule-hit-count/

As firewall rule sets grow in complexity, security teams face a common challenge: manual log analysis is used to determine which rules are actively matching traffic and which are consuming capacity without being triggered. This lack of visibility creates operational and compliance gaps. Organizations with governance policies that require removal of dormant rules after a defined period have no mechanism to identify them. Teams responsible for compliance frameworks such as Payment Card Industry (PCI) 4.0 and Digital Operational Resilience Act (DORA) can’t provide evidence that specific controls are actively functioning. Central teams managing firewalls on behalf of multiple business units have no way to determine which rules are unused or need updating.

In this post, you learn how a new AWS Network Firewall capability—rule hit count—addresses these challenges by providing traffic match data for stateful rules across both custom and managed rule groups. With this data, you can identify and remove unused rules, accelerate incident response, and validate security control effectiveness for compliance.

How it works

Rule hit counts track how often each stateful rule matches network traffic. The hit counter increments only when a rule match results in an alert log being created. This means any rule with an alert, drop, or reject action will increment the hit counter, because these actions generate alert logs. However, rules configured with a pass action don’t generate alert logs by default, meaning they won’t appear in the rule hit count metric.

To gain visibility into traffic matching pass rules, you can include the alert keyword within the pass rule. This generates an alert log while still permitting the traffic to its intended destination. The following Suricata rule demonstrates this approach:

pass tls $HOME_NET any -> $EXTERNAL_NET 443 (msg:"Pass and Log HTTPS traffic"; alert; sid:1000001; rev:1;)

This rule passes HTTPS traffic to its destination while also generating an alert log, making sure the rule appears in the hit count metric.

The rule hit count feature adds the following metadata to each alert log. Metadata is included by default and doesn’t require additional configuration:

“aws_metadata": { “resource_arn": “arn:aws:network-firewall:us-east-1:123456789012:stateful-rulegroup/StatefulRuleGroup” }

The following example shows a complete alert log with this metadata included:

{ 

    "firewall_name": "egress-and-east-west-firewall", 

    "availability_zone": "us-east-1a", 

    "event_timestamp": "1786112515", 

    "event": { 

        "tx_guessed": true, 

        "aws_category": "", 

        "tx_id": 0, 

        "app_proto": "http", 

        "ip_v": 4, 

        "src_ip": "10.2.1.205", 

        "src_port": 46240, 

        "event_type": "alert", 

        "alert": { 

            "severity": 3, 

            "signature_id": 10000003, 

            "rev": 0, 

            "signature": "Egress HTTP but not port TCP/80", 

            "action": "blocked", 

            "category": "" 

        }, 

        "ts_progress": "request_complete", 

        "flow_id": 927132830538451, 

        "dest_ip": "3.226.253.175", 

        "proto": "TCP", 

        "verdict": { 

            "action": "drop" 

        }, 

        "http": { 

            "hostname": "3.226.253.175", 

            "http_port": 4444, 

            "url": "/", 

            "http_user_agent": "curl/8.17.0", 

            "http_method": "GET", 

            "protocol": "HTTP/1.1", 

            "length": 0 

        }, 

        "tc_progress": "response_started", 

        "dest_port": 4444, 

        "pkt_src": "geneve encapsulation", 

        "aws_metadata": { 

            "resource_arn": "arn:aws:network-firewall:us-east-1:123456789012:stateful-rulegroup/StatefulRuleGroup" 

        }, 

        "timestamp": "2026-08-07T14:21:55.611810+0000", 

        "direction": "to_server" 

    } 

} 

The alert log data in the preceding example is the source for rule hit count metrics. Network Firewall pushes these alert logs to your Amazon CloudWatch Logs or Amazon Simple Storage Service (Amazon S3). To identify the specific rule that generated an alert, you can search using the combination of the sid (signature ID) and resource_arn fields. The firewall monitoring dashboard uses these fields to generate hit counts for each rule, so you can review rule activity directly on the dashboard without querying logs.

You can also access and analyze this data by querying those logs directly using CloudWatch Logs Insights for logs stored in CloudWatch, or Amazon Athena for logs stored in Amazon S3.

Getting started

Network Firewall rule hit count is enabled by default, so you don’t need to perform any additional configuration to start tracking rule hits on your firewall policies. This means that as soon as you deploy your firewall rules, you can begin to monitor which rules are being triggered, helping you gain visibility into your traffic patterns and identify potential security concerns.

Prerequisites

This walkthrough requires an existing network firewall configured to inspect traffic from your Amazon Virtual Private Cloud (Amazon VPC). If you don’t have one set up yet, follow the Getting started with AWS Network Firewall guide.

Additionally, ensure the following:

  1. Alert log delivery must be configured: The firewall must have alert logging enabled. Note that rule hit count metadata is captured regardless of log destination; however, the native dashboard feature requires logs to be sent to CloudWatch Logs or Amazon S3.
  2. Firewall monitoring must be enabled: To see the dashboard widget shown in figure 1, you must enable detailed monitoring through the firewall’s logging configuration or the Monitoring tab in the AWS Management Console for AWS Network Firewall. However, if you have a custom dashboard solution, the metadata required for rule hit count analysis is automatically included in the firewall logs regardless of whether detailed monitoring is enabled—so you can build your own visualizations using the log data directly.
  3. Pass rules must include the alert keyword to appear in hit count metrics: Rules configured with a pass action don’t generate alert logs by default. To track pass rule activity in the hit count metric, include the alert keyword in your pass rules, as demonstrated in the How it works section of this post.

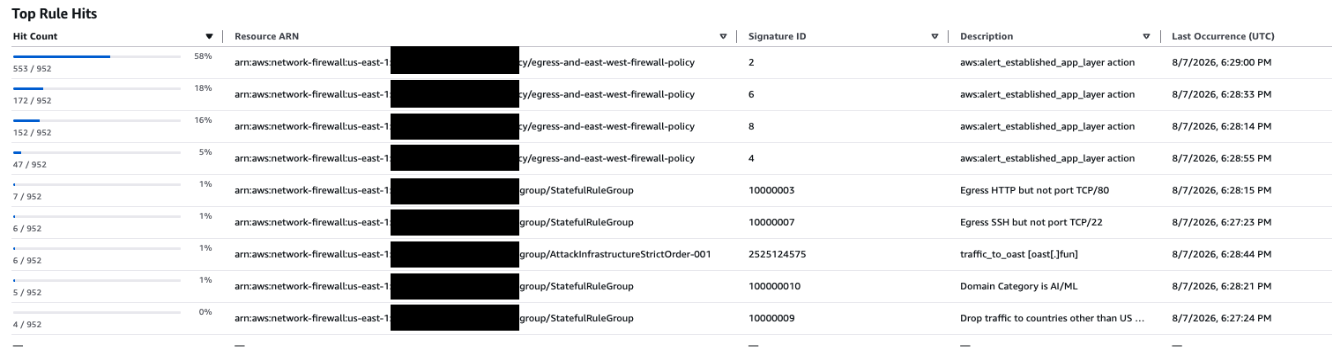
The Top Rule Hits dashboard shows aggregated hit counts per firewall across all Availability Zones within the AWS Region where that firewall is deployed. To view rule hit count metrics, open the Network Firewall console and select your firewall. Navigate to the Monitoring and observability section. Under Top analysis, you will see the Top Rule Hits metric. Select a lookback period to view rule activity within that timeframe.

Figure 1: Rule hit count from the dashboard

Figure 1: Rule hit count from the dashboard

Figure 1 shows the Top Rule Hits panel from the AWS Network Firewall console, displaying the most frequently triggered stateful rules. It includes columns for Hit Count (with bar chart and fraction), percentage of total hits, Resource ARN, Signature ID, Description (the msg field from the Suricata rule), and Last Occurrence (UTC).

Signature IDs 2, 4, 6, and 8 are system-generated signatures corresponding to the firewall policy’s strict order default actions. Because these signatures originate from the policy rather than a rule group, the resource_arn field displays the firewall policy Amazon Resource Name (ARN) instead of a rule group ARN. They appear in the Top Rule Hits when the policy has default actions such as Drop established, Alert established, or their application-layer variants configured. These signatures fire on established connection packets that don’t match any explicit rule, enforcing the policy’s default deny posture.

The following examples demonstrate how rule hit counts help you address common operational challenges.

  • Identifying unused rules: Figure 1 shows all rule signature IDs and their descriptions (the msg field from the Suricata rule) that actively matched traffic during the selected lookback period. Any rule in your firewall policy whose signature ID doesn’t appear in this metric hasn’t matched any traffic during the specified timeframe. These rules are either stale or not ordered correctly within your rule group.
  • Accelerating incident response: Figure 1 shows signature ID 2525124575 (traffic_to_oast [oast[.]fun]) with six hits and a last occurrence of August 7, 2026, at 6:28:44 PM UTC. This rule is detecting traffic to an out-of-band application security testing (OAST) domain, which could indicate an attacker attempting to exfiltrate data or validate a vulnerability in your environment. By filtering the top rule hits metric to the timeframe of a suspected incident, your team can quickly identify this type of suspicious activity and scope the impact without manually parsing thousands of log entries.
  • Validating a newly added rule: Figure 1 shows signature ID 100000010 (Domain Category is AI/ML) with five hits and a last occurrence of August 7, 2026, at 6:28:21 PM UTC. After adding this rule to monitor or restrict traffic to AI/ML related domains, the hit count confirms the rule is actively matching traffic as intended. Similarly, signature ID 100000009 (Drop traffic to countries other than US) shows four hits, validating that the geofencing rule is functioning and blocking outbound connections to destinations outside the United States. These hit counts provide security teams with concrete evidence that newly deployed controls are working.

Pricing

Rule hit counts are included with Network Firewall at no additional cost. However, standard charges apply for storing and querying log data. If you configure log delivery to CloudWatch Logs, CloudWatch pricing applies. If you store logs in Amazon S3 and query them with Athena, standard Amazon S3 storage and Athena query charges apply. For complete pricing details, see AWS Network Firewall pricing.

Considerations

Keep the following in mind when you use rule hit counts:

  • To manage costs, review your log utilization and configure log filtering or retention policies.
  • Rule hit counts apply to stateful rules. Stateless rules don’t support hit count tracking at this time.
  • Rule hit counts are available in all AWS Regions where AWS Network Firewall is supported, except Middle East (UAE) and Middle East (Bahrain).

Conclusion

In this post, you learned how rule hit counts in AWS Network Firewall give you visibility into your firewall rule utilization and effectiveness. By tracking how frequently each rule matches traffic, you can identify unused or redundant rules, optimize rule ordering, validate security controls for compliance, and respond faster during security investigations. For more information, see AWS Network Firewall.

If you have feedback about this post, submit comments in the Comments section below.

Preetkumar Shah

Preetkumar Shah

Preetkumar is a Technical Account Manager at AWS, based in Atlanta, GA. He specializes in helping customers design and operate secure, scalable network architectures in the cloud. At AWS, he works with SMB customers and collaborates closely with service teams to proactively resolve complex challenges and ensure customers get the most from their AWS environment. Outside of work, his interests include spending time with family and going on trails.

Amit Gaur

Amit Gaur

Amit, a Cloud Infrastructure Architect at AWS, brings his passion for technology and knowledge-sharing to the networking community. Specializing in network architecture design, he helps customers build highly scalable and resilient environments on AWS. Through technical guidance and architectural expertise, Amit enables customers to accelerate their cloud adoption journey while making sure their systems are built for scale and reliability.

Santosh Shanbhag

Santosh is a seasoned product leader, specializing in security, data protection, and compliance. At AWS, he focuses on securing workloads through Network and Application Security services, including AWS Network Firewall and active threat defense.

Srivalsan Mannoor Sudhagar

Srivalsan is a Sr. Cloud Infrastructure Architect at Amazon Web Services Professional Services who brings expertise in Cloud Infrastructure and MLOps solutions. He is passionate about networking, container technologies and loves to innovate to help solve customer problems. He enjoys architecting solutions and providing technical guidance to help customers and partners achieve their technical and business objectives.

Cheriyan Mundapuzha

Cheriyan Mundapuzha

Cheriyan, a Cloud Infrastructure Architect at AWS, brings his infrastructure experience to some of the most complex migration challenges in the enterprise space. Through published architectural patterns, hands-on technical leadership, and mentorship of fellow professionals, he enables customers to accelerate their modernization journey while ensuring their systems are built for resilience and operational excellence.

Propagate user authorization context in AI agents with Amazon Bedrock AgentCore

Post Syndicated from Anshu Bathla original https://aws.amazon.com/blogs/security/propagate-user-authorization-context-in-ai-agents-with-amazon-bedrock-agentcore/

Many teams now deploy AI agents that pull from Amazon DynamoDB tables, document repositories, software as a service (SaaS) platforms, and internal knowledge bases to answer questions and automate workflows. A key risk in these deployments is that the agent has no awareness of who’s asking, so it might return data the user shouldn’t see.

If you’re using Amazon Bedrock AgentCore to build AI agents that access multiple data sources, you need each user to see only the data they’re authorized to access. In this post, you learn patterns for propagating user authorization context through your agents so access control is enforced by infrastructure and downstream services, not by agent code. In this post, we show you how to deploy agents that enforce least privilege access without writing authorization logic in the agent itself. This approach follows AGENTSEC03 best practice in the AWS Well-Architected Agentic AI Lens.

Use case

Consider an example of a customer relationship management (CRM) chat application where employees from Sales and Finance departments interact with an AI agent to access customer information. Employees use the same chat interface and the same agent, but each department needs isolated access to their respective data:

  • Sales needs access to customer contracts, pricing strategies, and sales pipeline data
  • Finance needs access to customer invoices, payment records, and financial reports

The AI agent accesses three types of data sources on behalf of users:

When a Sales employee asks, “Show me customer contracts,” the agent must retrieve only Sales department contracts, not Finance invoices. This enforcement must happen outside the agent so that even if the agent is compromised through prompt injection or application bugs, it can’t access unauthorized data.

Note: Although we use department-based scoping in this example, the pattern generalizes to any custom claim you define, whether it represents a role, business unit, geographic region, or project assignment.

Architecture overview

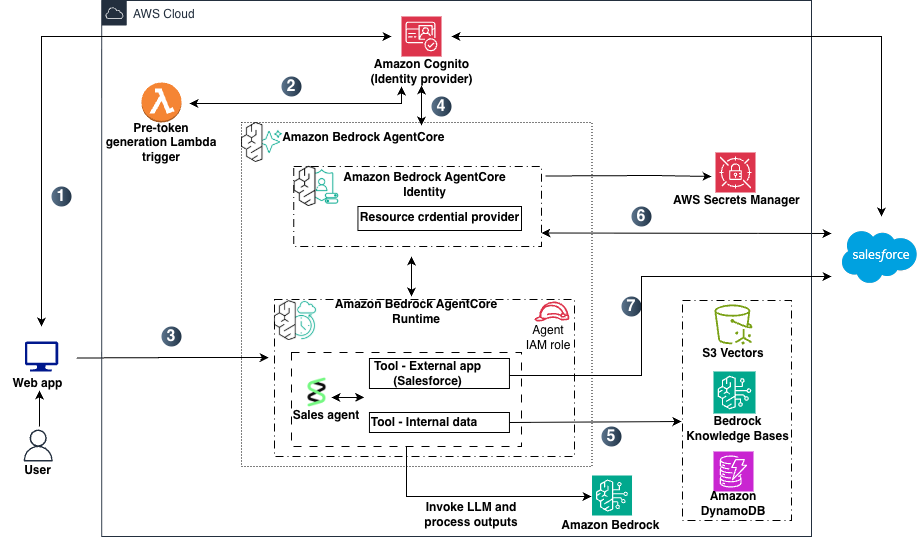
The following diagram shows the architecture used in this demonstration.

Figure 1: Target architecture

Figure 1: Target architecture

The data flow shown in Figure 1 includes:

  1. A user opens the chat application and authenticates with Amazon Cognito user pool , which acts as the identity provider (IdP).
  2. A pre token generation Lambda trigger (V2) enriches the JSON Web Tokens (JWTs) with a custom claim and AWS session tag metadata before returning them to the user.
  3. The web app routes the user’s request along with the access token to the agent deployed on Amazon Bedrock AgentCore Runtime.
  4. Bedrock AgentCore Runtime validates the inbound JWT and, through Bedrock AgentCore Identity, issues a workload access token that binds the user and agent identities, and then invokes the agent.
  5. For queries requiring internal documents, the agent uses its AWS Identity and Access Management (IAM) role to query Amazon Bedrock Knowledge Bases (backed by an Amazon S3 vector store) with metadata filtering, and DynamoDB with user-scoped session-tagged credentials.
  6. For queries requiring external data, Bedrock AgentCore Identity retrieves credentials from AWS Secrets Manager and performs an on-behalf-of token exchange (RFC 8693) with Salesforce, returning a user-scoped access token.
  7. The agent calls the Salesforce REST API using the user-scoped token. Salesforce applies sharing rules and returns only records the user is authorized to access.

This architecture follows two key principles.

  • The agent acts as an orchestrator, not a gatekeeper; it coordinates tool calls and reasoning but doesn’t control access to data. Authorization is enforced by downstream services.
  • The agent doesn’t store credentials to data stores; instead, each request gets temporary, user-bound access tokens.

In the following sections, we dive deep into each data source to show how these principles are achieved in practice.

Initial user authentication with IdP

When an employee opens the chat application, they authenticate using their corporate credentials. For this example, you use Amazon Cognito user pools as the IdP. You can also achieve this with other IdPs such as Entra ID or Okta.

The pre token generation Lambda trigger (V2) captures the user’s custom department context and adds it to the tokens to both the identity (ID) token and access token that Bedrock AgentCore Runtime uses for authorization decisions each serving a distinct purpose. The access token is used by the Bedrock AgentCore Runtime custom JWT authorizer for inbound authorization. The ID token also receive the https://aws.amazon.com/tags claim (used by AWS Security Token Service (AWS STS)) for session tags). The https://aws.amazon.com/tags claim is the specific format required by AWS STS to extract session tags during AssumeRoleWithWebIdentity. For more information and step-by-step guidance see How to customize access tokens in Amazon Cognito user pools.

The following example shows the key logic within a pre token generation Lambda handler function configured as a trigger on your Amazon Cognito user pool. This code runs automatically when a user authenticates, extracting their department attribute and adding it as a custom claim to both ID Token and access token.

import json

def lambda_handler(event, context):
    department = event['request']['userAttributes'].get('custom:department', '')

    event['response']['claimsAndScopeOverrideDetails'] = {
        'idTokenGeneration': {
            'claimsToAddOrOverride': {
                'department': department,
                'https://aws.amazon.com/tags': {
                    "principal_tags": {"department": [department]},
                    "transitive_tag_keys": ["department"]
                }
            }
        },
        'accessTokenGeneration': {
            'claimsToAddOrOverride': {
                'department': department
            }
        }
    }
    return event

Inbound authorization by AgentCore Runtime

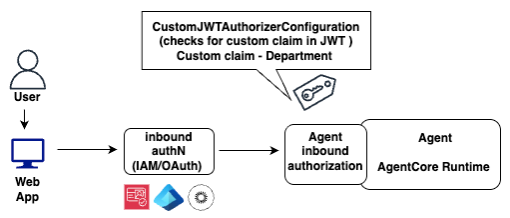
When the user request reaches AgentCore Runtime, the Inbound JWT authorizer performs two checks as shown in Figure 2. It validates the JWT token with Amazon Cognito (the configured IdP) by cryptographically verifying the token’s signature, confirming it is non-expired, and checking it was issued by the trusted IdP. It then extracts the department claim from the validated token and compares it against the expected value configured in the authorizer, any token without a matching claim is rejected before the agent code is invoked.

Figure 2: Inbound JWT authorization

Figure 2: Inbound JWT authorization

The following example shows the inbound JWT authorizer configuration that you pass when deploying your agent to AgentCore Runtime. This configuration tells AgentCore which IdP to validate against and which custom claim value to enforce for this agent. In this example, inboundTokenClaimName is department, inboundTokenClaimValueType declares the claim type as STRING_ARRAY, and authorizingClaimMatchValue specifies the allowed values ([“Sales”, “Finance”]) with the CONTAINS_ANY operator. The authorizer validates that the department claim is present in the token and matches one of these values, ensuring only authenticated users from the Sales or Finance department can invoke the agent.

authorizer_config = {
        "customJWTAuthorizer": {
            "discoveryUrl": discovery_url,
            "allowedClients": [client_id],
            "customClaims": [
                {
                    "inboundTokenClaimName": "department",
                    "inboundTokenClaimValueType": "STRING_ARRAY",
                    "authorizingClaimMatchValue": {
                        "claimMatchValue": ["Sales", "Finance"]
                        "claimMatchOperator": "CONTAINS_ANY"
                    }
                }
            ]
        }
    }

Note: AgentCore Runtime automatically creates a workload identity for each deployed agent. A workload identity represents the digital identity of your agents within the AWS environment. It allows agents to maintain consistent identity whether they’re using IAM roles for AWS resource access, OAuth 2.0 tokens for external service integration, or API keys for third-party tool access.

Passing the user context for agent outbound authorization

After the inbound JWT token is validated and the user’s authorization context is confirmed, the agent must propagate this context to downstream resources. The fundamental security challenge here is how to design a system so that an agent acting on behalf of a user can only access data that user is authorized to see, even if the agent itself is compromised.

The traditional approach of granting the agent broad credentials and relying on application-level filtering (such as adding WHERE clauses to queries) creates a single point of failure. If an attacker manipulates the agent through prompt injection or exploits a bug in the filtering logic, the full dataset becomes accessible. A more resilient design moves authorization enforcement out of the agent’s application code and into the infrastructure layer wherever possible. Instead of trusting the agent to filter results correctly, you configure the underlying services—IAM policies, database access controls, SaaS sharing rules—to reject unauthorized requests regardless of what the agent asks for. This way, the agent’s credentials are inherently limited to the requesting user’s permissions, and no amount of prompt manipulation can bypass those boundaries. Where infrastructure-level enforcement isn’t yet available, such as metadata filtering in Amazon Bedrock Knowledge Bases, the agent applies application-layer controls as a complementary measure. The following sections demonstrate how this principle applies to each data source in our architecture.

Pattern 1: Scoping DynamoDB access to the requesting user

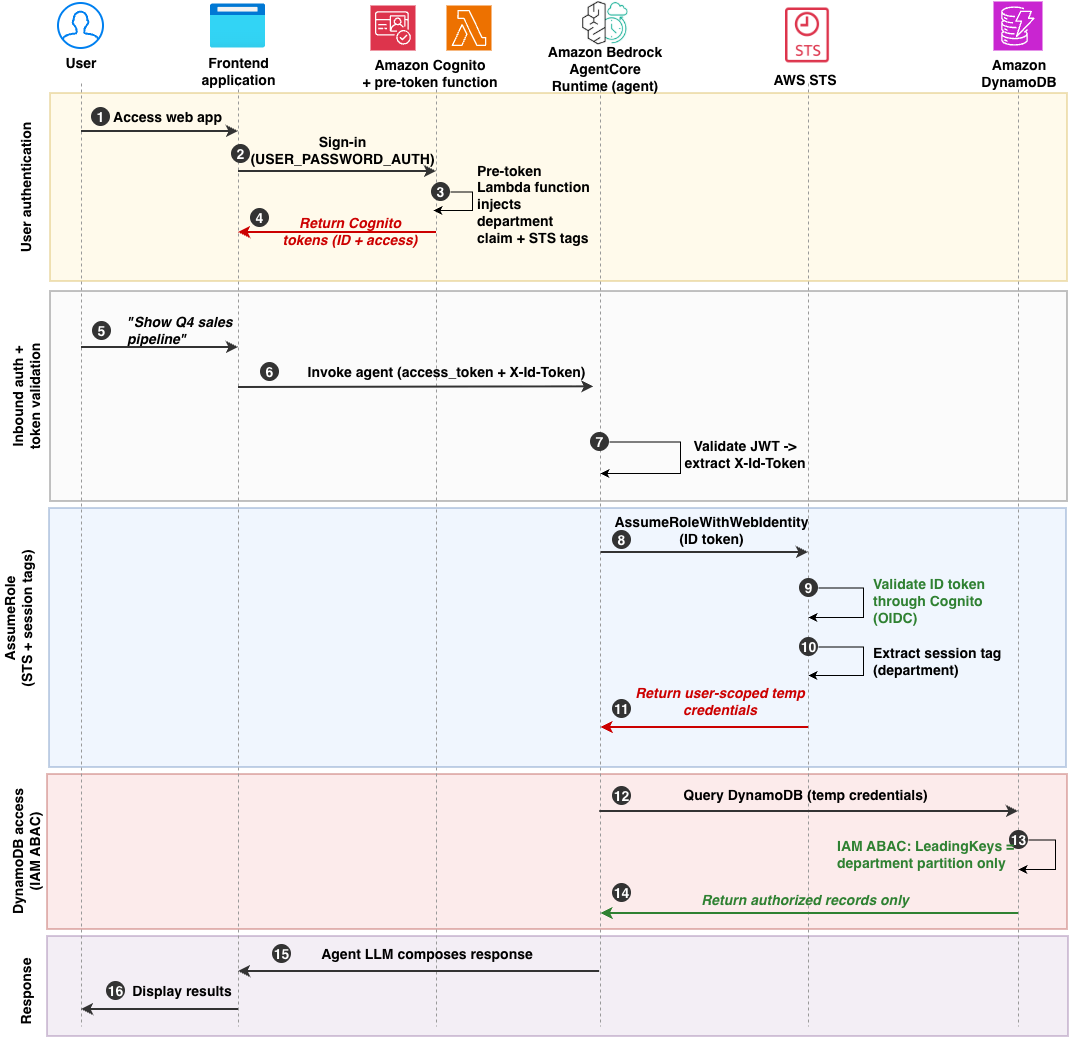
For DynamoDB access, you can use AssumeRoleWithWebIdentity with session tags to create per-request, user-scoped credentials rather than granting the agent a static IAM role with direct table access. The agent passes the user’s signed ID token to AWS STS, which extracts the department tag from the token’s https://aws.amazon.com/tags claim and returns temporary credentials constrained to that department’s data partition. This moves access control from agent code to IAM policy evaluation. STS additionally validates the token’s audience (aud) claim against the IAM OIDC provider configuration, preventing tokens issued for other app clients from being used to assume the role. The following diagram shows this flow (Figure 3).

Prerequisites (one-time setup):

Before this runtime flow can execute, complete the following configuration:

  • Register Amazon Cognito as an IAM OIDC provider. Although the user authenticates using the Cognito API (USER_PASSWORD_AUTH), STS requires Cognito to be registered as an OIDC provider so it can discover and validate ID tokens. Configure the allowed client IDs (audiences) on the provider to match your application’s app client ID.
CognitoOIDCProvider:
  Type: AWS::IAM::OIDCProvider
  Properties:
    Url: !Sub 'https://cognito-idp.${AWS::Region}.amazonaws.com/${CognitoUserPoolId}'
    ClientIdList:
      - !Ref CognitoAppClientId
    ThumbprintList:
      - '<thumbprint>'

  • Configure the UserScopedDynamoDBRole trust policy to include both sts:AssumeRoleWithWebIdentity and sts:TagSession permissions, with the Amazon Cognito OIDC provider as the federated principal.
{
  "Version": "2012-10-17",
  "Statement": [{
    "Effect": "Allow",
    "Principal": {
      "Federated": "arn:aws:iam::111122223333:oidc-provider/cognito-idp.us-east-1.amazonaws.com/us-east-1_EXAMPLE"
    },
    "Action": [
      "sts:AssumeRoleWithWebIdentity",
      "sts:TagSession"
    ],
    "Condition": {
      "StringEquals": {
        "cognito-idp.us-east-1.amazonaws.com/us-east-1_EXAMPLE:aud": "<app-client-id>"
      }
    }
  }]
}

  • By default, AgentCore Runtime drops custom headers as a security measure. To allow the X-Id-Token header through to the agent container, configure it in the agent runtime’s requestHeaderAllowlist so the ID token is forwarded to agent code. The following configuration tells AgentCore Runtime to forward only the X-Id-Token header to agent code, dropping other non-standard headers:
request_header_config = {
    'requestHeaderAllowlist': ['X-Id-Token']
}

How it works:

  1. The user navigates the web application.
  2. The user authenticates with Amazon Cognito using USER_PASSWORD_AUTH.
  3. The JWT is issued with a custom department claim and the https://aws.amazon.com/tags claim for STS session tagging (covered in the preceding Initial user authentication with IdP section).
  4. Amazon Cognito returns the enriched tokens to the frontend. The access token carries the department claim for inbound authorization. The ID token carries both the department claim and the https://aws.amazon.com/tags claim for downstream STS calls.
  5. The user asks the agent a question (for example, “Show Q4 sales pipeline”).
  6. The frontend calls AgentCore Runtime, passing two tokens: the Amazon Cognito access token in the Authorization header (for inbound authorization), and the user’s ID token as a custom X-Id-Token header (for downstream STS calls).
  7. AgentCore Runtime validates the JWT and verifies the department claim matches the allowed values configured in the inbound authorizer. If validation fails, the request is rejected with HTTP 401 before agent code executes. After validation, AgentCore forwards the request to the agent container along with the allowed X-Id-Token header.
  8. The agent calls sts:AssumeRoleWithWebIdentity with the ID token. This call targets a single shared UserScopedDynamoDBRole. The following is the agent code for this step:
    def _scoped_dynamodb_resource(id_token: str):
        """Assume user-scoped role and return DynamoDB resource."""
        sts = boto3.client('sts')
        response = sts.assume_role_with_web_identity(
            RoleArn=USER_SCOPED_DYNAMODB_ROLE_ARN,
            RoleSessionName="agent-user-session",
            WebIdentityToken=id_token,
            DurationSeconds=900
        )
        creds = response['Credentials']
        session = boto3.Session(
            aws_access_key_id=creds['AccessKeyId'],
            aws_secret_access_key=creds['SecretAccessKey'],
            aws_session_token=creds['SessionToken']
        )
        return session.resource('dynamodb')

  9. AWS STS validates the token against the Amazon Cognito OIDC provider registered in IAM. STS verifies the token’s cryptographic signature, expiration, issuer, and audience (aud). The aud claim in the ID token must match one of the client IDs configured on the IAM OIDC provider resource. This prevents a valid token issued by the same Cognito user pool but for a different app client from being accepted. Note that the agent’s own execution role has no DynamoDB access and only permits sts:AssumeRoleWithWebIdentity, so even a compromised agent can’t bypass this flow.

    Note: Amazon Cognito user pools expose a standard OpenID Connect discovery endpoint, which is what you register as the trusted OIDC provider in IAM, even though the user signs in through the Cognito authentication APIs. When STS validates the token, it checks that the aud claim matches the client ID configured in the IAM OIDC provider. Tokens whose audience doesn’t match are rejected, adding a second control alongside signature and issuer validation.

  10. AWS STS extracts the https://aws.amazon.com/tags claim and creates a session with aws:PrincipalTag/department set. The trust policy’s sts:TagSession permission (configured in the prerequisites) enables this. Without it, STS silently drops the session tags and subsequent access is denied.
  11. AWS STS returns temporary credentials. These credentials are user-scoped and tamper-proof because the session tags are derived from the cryptographically signed JWT, not from agent code.
  12. The agent queries DynamoDB using these credentials.
  13. IAM evaluates the dynamodb:LeadingKeys condition against ${aws:PrincipalTag/department}. Only the user’s department partition is accessible. Because IAM evaluates this condition at the policy level, even if agent code is manipulated using prompt injection, cross-department access is denied. The following is an example of the permission policy on the role:
    {
      "Version": "2012-10-17",
      "Statement": [{
        "Effect": "Allow",
        "Action": ["dynamodb:GetItem", "dynamodb:Query"],
        "Resource": "arn:aws:dynamodb:us-east-1:111122223333:table/CustomerRecords",
        "Condition": {
          "ForAllValues:StringEquals": {
            "dynamodb:LeadingKeys": ["${aws:PrincipalTag/department}"]
          }
        }
      }]
    }

  14. DynamoDB returns only the records from the user’s authorized department partition. Cross-department data is never returned because the IAM policy blocks the API call itself. It doesn’t rely on post-query filtering.
  15. The agent receives the authorized results and passes them to the LLM for natural language response composition.
  16. The composed response is returned to the frontend application and displayed to the user.

Pattern 2: User-scoped authorization to Amazon Bedrock Knowledge Bases

For documents stored in Amazon Bedrock Knowledge Bases, the agent applies metadata filtering at query time. Each document is tagged with a Department metadata attribute during ingestion. Amazon Bedrock Knowledge Bases using metadata filtering to implement the data authorization. You need to provide metadata files alongside the source data files with the same name as the source data file and .metadata.json suffix while uploading data in Amazon S3. Amazon Bedrock Knowledge Bases ingests these documents along with corresponding metadata file. The metadata attributes are stored alongside the vectors as filterable fields in the index.

Each metadata file contains a simple JSON structure with the department attribute. The following example shows the complete content of a metadata file for Sales department documents:

{"metadataAttributes": {"Department": “Sales"}}

When the agent queries Amazon Bedrock Knowledge Bases, it calls the bedrock:Retrieve action and appends the retrievalConfiguration filter scoped to the user’s department. The department value is extracted from the JWT access token that the agent received during inbound authorization.

response = client.retrieve(
    knowledgeBaseId=KNOWLEDGE_BASE_ID,
    retrievalQuery={"text": user_query},
    retrievalConfiguration={
        "vectorSearchConfiguration": {
            "filter": {"equals": {"key": "Department", "value": department}}
        }
    }
)

Note: Metadata filtering is application-layer enforcement. The bedrock:Retrieve API doesn’t expose metadata filter content as an IAM condition key. For stricter isolation, consider separate knowledge bases per department with IAM resource-level policies.

Pattern 3: User-scoped access to external services using on-behalf-of token exchange

We use Salesforce as an example of an external service integration. The same on-behalf-of (OBO) token exchange pattern applies to external service that supports RFC 8693 or a compatible token exchange mechanism. External services like Salesforce don’t support IAM-based access control, so you need a different mechanism to propagate user identity. The AgentCore Identity OBO token exchange (RFC 8693) provides this by exchanging the user’s authenticated identity for a user-scoped token that the external service will recognize and enforce natively.

AgentCore Identity supports three OAuth patterns for external service access. With client credentials—Two-Legged OAuth (2LO) or machine-to-machine (M2M)—the agent authenticates as a service account and receives a token with broad access. The agent is then responsible for filtering data in queries, which makes this pattern suitable when accessing organization-wide data that isn’t scoped to an individual user. A variation of this pattern embeds user context as custom claims within the agent’s M2M token itself, see Empower AI agents with user context using Amazon Cognito. With Authorization Code (3LO), the user explicitly consents through a browser redirect and the external service enforces per-user access. This works when per-service consent is required, but it demands user interaction during the flow, making it impractical for background agent operations. Learn more about this in Secure AI agents with Amazon Bedrock AgentCore Identity on Amazon ECS. With OBO token exchange, the user’s already-authenticated identity is exchanged for a service-scoped token without any additional user interaction, and the external service enforces access.

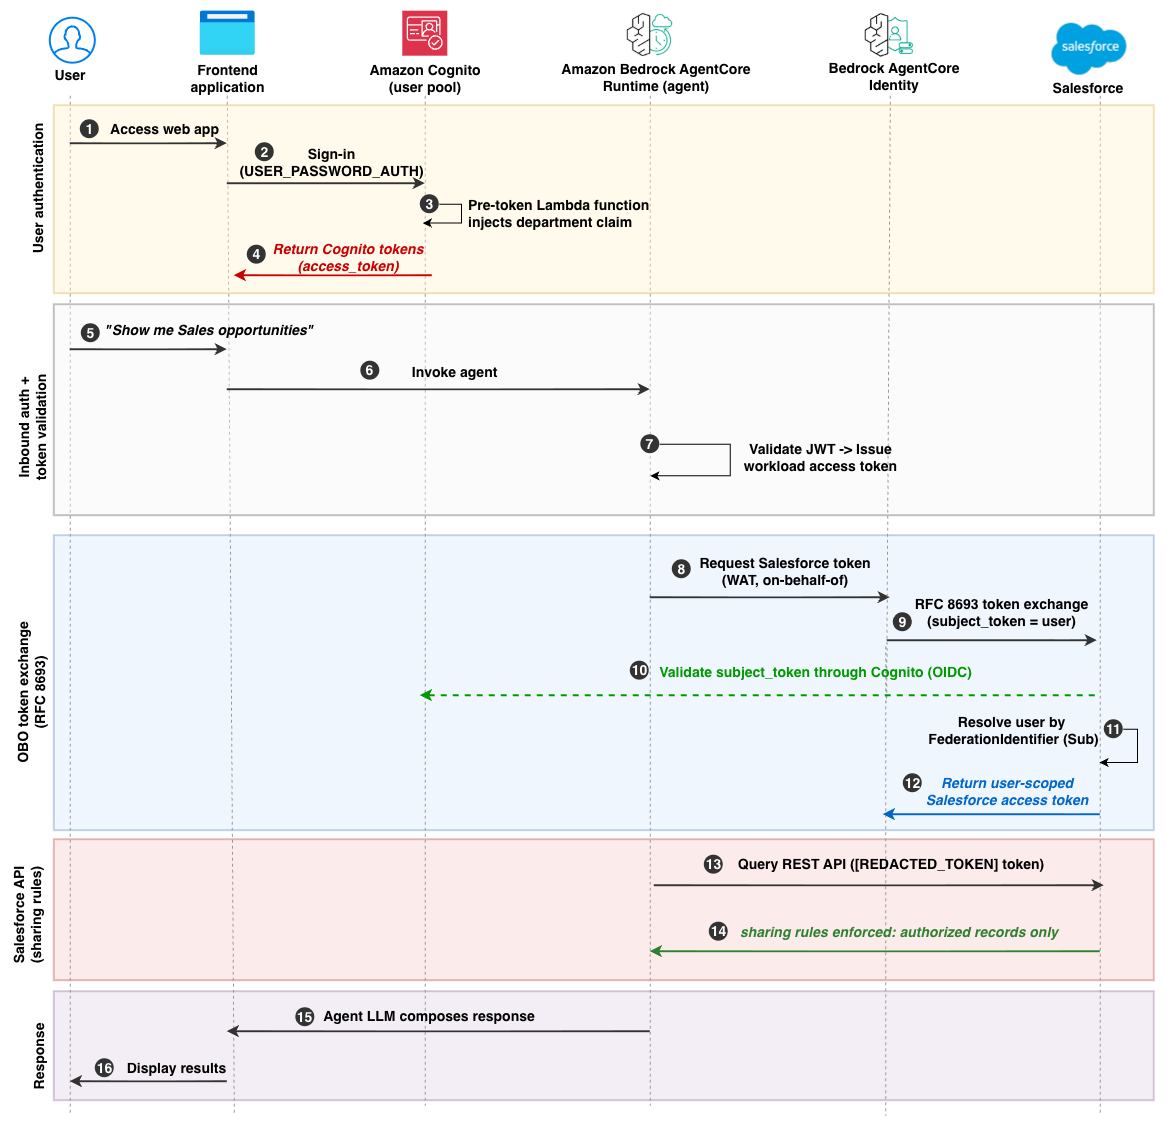
For this use case, OBO is the most appropriate pattern. The user has already authenticated at the entry point (through the IdP), and the agent needs to act on their behalf across multiple services without prompting for additional consent. OBO propagates user identity end-to-end without the agent holding credentials, scales automatically with no per-user token storage, and allows downstream services to enforce their own authorization (sharing rules, role-based access control (RBAC)). Because no browser redirect is needed, OBO works seamlessly for background tool calls where the user isn’t present in a browser session. Figure 4 demonstrates the complete flow when using OBO token exchange.

How it works:

  1. The user navigates to the web application.
  2. The user authenticates with Amazon Cognito using USER_PASSWORD_AUTH.
  3. A pre token generation Lambda function injects the custom department claim into the token (covered in the preceding Initial user authentication with IdP section).
  4. Amazon Cognito returns the tokens to the frontend. The access token is issued with the department claim.
  5. The user asks the agent a question (for example, “Show me Sales opportunities”).
  6. The frontend calls AgentCore Runtime with a single agent Amazon Resource Name (ARN), passing the Amazon Cognito access token: POST /invocations, Authorization: Bearer {access_token}.
  7. AgentCore Runtime validates the inbound JWT (signature, expiration, issuer, and custom claims including the department claim). After successful validation, AgentCore Runtime extracts the user identity from the JWT and calls the GetWorkloadAccessTokenForJWT API to exchange it for a workload access token. The agent code receives the workload access token through the invocation payload header. Workload access tokens are exclusively for accessing Amazon Bedrock AgentCore services and can’t be used directly for external services.
  8. The agent calls AgentCore Identity (GetResourceOauth2Token) with the workload access token, requesting a Salesforce token through the configured OBO (on-behalf-of) credential provider. AgentCore Identity validates the caller identity and agent identity, then accesses the stored client credentials from Secrets Manager. If a previously stored OAuth access token has expired, AgentCore Identity automatically obtains a new one using the client credentials, reducing the need for manual token lifecycle management in agent code. The agent code uses the @requires_access_token decorator to invoke this flow:
    @requires_access_token(
        provider_name="salesforce-token-exchange",
        scopes=[],
        auth_flow="ON_BEHALF_OF_TOKEN_EXCHANGE",
    )
    def _get_salesforce_token_sync(*, access_token: str) -> str:
        return access_token

    On the AWS side, this requires an AgentCore Identity OAuth Client configured with Grant type: Token Exchange, Actor token: None, pointing to the Salesforce token endpoint. The Salesforce Connected App consumer secret is stored in Secrets Manager (the agent doesn’t access it directly).

  9. AgentCore Identity performs RFC 8693 token exchange with the Salesforce token endpoint, sending the user identity as the subject_token. AgentCore Identity performs this secure token exchange for user-delegated access based on the configured OAuth 2.0 credential provider. The agent can’t request tokens for arbitrary users because the workload access token cryptographically binds the request to the authenticated user.
  10. Salesforce validates the token against the registered Amazon Cognito auth provider configured in Salesforce Setup.
  11. Salesforce resolves the user using FederationIdentifier. On the Salesforce side, this requires:
    • Amazon Cognito registered as an OpenID Connect auth provider
    • A token exchange handler (Apex class extending Auth.Oauth2TokenExchangeHandler) that resolves users by FederationIdentifier
    • Token exchange flow enabled on the connect app or external client app
    • Each user’s FederationIdentifier set to their Amazon Cognito subject’s (sub) unique user identifier (UUID).
    • Sharing rules configured to enforce department-scoped record access

    The federation ID (sub) is immutable and can’t be spoofed by the agent, because it originates from the cryptographically signed identity token.

  12. Salesforce returns a user-scoped access token to AgentCore Identity, which passes it back to the agent.
  13. Agent calls the Salesforce REST API using the user-scoped token. No department filtering is needed in the Salesforce Object Query Language (SOQL) query because Salesforce enforces access through sharing rules:
    @tool
    def query_salesforce_opportunities(query_text: str) -> str:
        access_token = _get_salesforce_token_sync()
    
        # No department filter needed. Salesforce sharing rules enforce access.
        soql = "SELECT Id, Name, Amount, StageName, CloseDate FROM Opportunity ORDER BY CloseDate DESC LIMIT 10"
    
        response = requests.get(
            f"{SALESFORCE_URL}/services/data/v59.0/query?q={urllib.parse.quote(soql)}",
            headers={"Authorization": f"Bearer {access_token}"},
            timeout=30,
        )
        return json.dumps(response.json().get("records", []))

  14. Salesforce applies sharing rules and returns only records the user is authorized to access. The agent doesn’t hold Salesforce credentials (refresh tokens, client secrets), these remain with AgentCore Identity.
  15. The agent’s LLM composes a response from the returned records.
  16. The frontend displays the results to the user.

Conclusion

In this post, you learned how to enforce consistent, end-to-end authorization in agentic AI applications by propagating user context from Amazon Cognito through Amazon Bedrock AgentCore to downstream resources. We showed you three patterns:

  • Per-request user-scoped credentials using AssumeRoleWithWebIdentity with session tags, evaluated by IAM attribute-based access control (ABAC) policies to access Amazon DynamoDB
  • Department-scoped metadata filtering at the application layer to access Amazon Bedrock Knowledge Bases.
  • On-behalf-of token exchange (RFC 8693) using AgentCore Identity, with Salesforce-native sharing rules governing access to external CRM data.

The key takeaway is that the agent coordinates work but doesn’t decide who can access what. Access decisions are made by infrastructure-level controls and the downstream service’s authorization model. This layered approach means that even if the agent behaves unexpectedly, unauthorized data access is still blocked.

You can use this as a reference implementation and adapt it to your requirements by choosing authorization attributes relevant to your organization (such as department, role, business unit, or region), integrating additional data sources, or extending the token exchange patterns to other external services.

Next steps

If you have feedback about this post, submit comments in the Comments section below.

Anshu Bathla

Anshu Bathla

Anshu is a Sr. Lead Consultant – Security at AWS, based in Gurugram, India. He works with customers across diverse verticals to help strengthen their security infrastructure and achieve their security goals. Outside of work, Anshu enjoys reading books and gardening at his home garden. Connect with him on LinkedIn.

Prafful Gupta

Prafful Gupta

Prafful is a DevOps Engineer at AWS, based in Gurugram, India. Having started his professional journey with Amazon, he specializes in DevOps and generative AI solutions, helping customers navigate their cloud transformation journeys. Beyond work, he enjoys networking with fellow professionals and spending quality time with family. Connect with him on LinkedIn.

Rohit Verma

Rohit Verma

Rohit is a Delivery Consultant – Security, Risk and Compliance at AWS, based in Gurugram, India. He partners with customers across multiple industries to strengthen their security posture, leading risk consulting engagements, and security deliverable reviews. Outside of work, Rohit is a fitness enthusiast who enjoys music and reading non-fiction books. Connect with him on LinkedIn.

Implement custom authentication for tools integration using request Lambda interceptor in AgentCore Gateway

Post Syndicated from Nishant Mainro original https://aws.amazon.com/blogs/security/implement-custom-authentication-for-tools-integration-using-request-lambda-interceptor-in-agentcore-gateway/

When deploying AI agents with Amazon Bedrock AgentCore, organizations benefit from built-in modern support for OAuth 2.0, AWS Identity and Access Management (IAM), and API key authentication through Amazon Bedrock AgentCore Gateway. However, some enterprise environments still use legacy authentication mechanisms such as HTTP Basic Authentication (Basic Auth) (RFC 7617). The extensible architecture of AgentCore Gateway enables support for these authentication mechanisms through a request Lambda interceptor—custom code that runs each time an agent calls a tool.

In this post, we show you how to use a request Lambda interceptor to authenticate to a downstream tool API using system credentials, retrieving a service account credential from AWS Secrets Manager and constructing a Basic Auth header. This design keeps credentials isolated from the agent, designed to mitigate exposure through model-driven behavior such as prompt injection.

Important: Basic Auth is an antiquated technology that transmits credentials as Base64-encoded text and should not be used as a long-term authentication strategy. AWS recommends modernizing to OAuth 2.0, SAML, OpenID Connect, or IAM where possible. However, some organizations with legacy workloads choose to decouple authentication modernization from their agentic AI adoption, addressing each on independent timelines. If your environment requires Basic Auth integration as an interim measure, consult your AWS Solutions Architect to evaluate the security trade-offs before proceeding. We’re providing this post as a reusable implementation, but it shouldn’t be construed as an endorsement of Basic Auth, or considered suitable as a long-term solution.

Solution overview

The solution uses a request Lambda interceptor in AgentCore Gateway to retrieve system credentials and construct a Basic Auth header for the downstream tool API. Figure 1 shows the end-to-end flow.

Figure 1: Solution workflow

Figure 1: Solution workflow

  1. The AI agent initiates a tool call over Model Context Protocol (MCP) to the gateway with an inbound JSON Web Token (JWT) issued by a configured identity provider (IdP). The MCP request body contains the tool name and any required parameters. The gateway’s inbound authentication layer validates the token against the IdP specified in the inbound authorizer configuration.
  2. After inbound authentication succeeds, the gateway invokes the request Lambda interceptor, passing the original request payload and headers, including the validated JWT and its embedded claims.
  3. The request Lambda interceptor re-validates the inbound JWT issued by the configured IdP as a defense-in-depth measure, then retrieves the system service account credential from Secrets Manager. The credential is a service account that authenticates the AI agent to the downstream tool.
  4. The interceptor then constructs a compliant Basic Auth header using the system credential and adds it to the outbound request. Because Basic Auth transmits credentials as Base64-encoded text (not encrypted), you must implement relevant compensating controls (e.g., ensure that all communication with the downstream tool API is over TLS, conduct two-person review of Lambda code changes, and so on).

    Note: The system credential stored in Secrets Manager corresponds to a service account in Active Directory (AD). The credential lifecycle requires a one-time manual seed: a system administrator creates the service account in AD and stores the same initial credential in Secrets Manager (necessary because Secrets Manager can’t read a password back from AD). As a security best practice, trigger an immediate rotation after seeding to retire the human-known password using the built-in capabilities of Secrets Manager. From that point forward, Secrets Manager automates the rotation process, periodically generates a new password, and updates both Secrets Manager and AD simultaneously. This eliminates manual credential management in either system. At runtime, the request Lambda interceptor retrieves the current credential from Secrets Manager and presents it to the downstream tool, which validates it against AD. For implementation details on keeping both stores synchronized, see Rotate Active Directory credentials stored in AWS Secrets Manager.

  5. The AgentCore gateway forwards the adjusted request now carrying the custom authentication header to the downstream target tool.
  6. The downstream target tool authenticates the request, processes it, and returns the response to the gateway.
  7. The gateway relays the response back to the AI agent.

Implementation

The following steps walk through configuring the request Lambda interceptor and implementing the core of the authentication transformation logic. You can find the complete sample code at Implementing custom authentication for tools integration using Request Lambda Interceptor.

Step 1: Attach a request Lambda interceptor to your AgentCore Gateway

Configure the AgentCore gateway to invoke a request Lambda interceptor for authentication transformation before forwarding the request to the downstream tool.

Important: You must enable passRequestHeaders configuration. Without it, the request Lambda interceptor can’t receive the request header containing the inbound JWT, and the authentication pattern described in this post will not work.

The following example shows the gateway configuration:

import boto3 

bedrock_client = boto3.client('bedrock-agentcore-control', region_name='<your-region>') 
# e.g., region_name='us-west-2' 

bedrock_client.update_gateway( 
    gatewayIdentifier='<your-gateway-id>', 
    interceptorConfigurations=[
        { 
            'interceptor': { 
                'lambda': { 
                    'arn': 'arn:aws:lambda:<region>:<account-id>:function:<YourInterceptorFunction>' 
                } 
            }, 
            'interceptionPoints': ['REQUEST'], 
            'inputConfiguration': { 
                'passRequestHeaders': True 
            } 
        } 
    ] 
) 

Step 2: Validate the inbound JWT

The interceptor independently validates the JWT signature as a defense-in-depth measure, protecting against scenarios where the request Lambda interceptor could be invoked through a path that bypasses gateway validation. It fetches the identity provider’s JSON Web Key Set (JWKS) (cached across warm Lambda invocations to avoid repeated network calls), verifies the token’s signature, expiration, and issuer, then returns the decoded claims.

The following code demonstrates JWT validation:

  import jwt 
  from jwt import PyJWKClient 

  COGNITO_ISSUER = 
  f"https://cognito-idp.{COGNITO_REGION}.amazonaws.com/{YOUR_COGNITO_USER_POOL_I 
  D}" 
  jwk_client = PyJWKClient(f"{COGNITO_ISSUER}/.well-known/jwks.json") 

  def validate_jwt(token): 
      """Validate JWT signature and return decoded claims.""" 
      signing_key = jwk_client.get_signing_key_from_jwt(token) 
      return jwt.decode(token, signing_key.key, algorithms=["RS256"], 
  issuer=COGNITO_ISSUER) 

Step 3: Retrieve system credentials from Secrets Manager

The interceptor retrieves the system service account credential from Secrets Manager. This credential authenticates the AI agent to the downstream tool. The secret is encrypted with a customer-managed AWS Key Management Service (AWS KMS) key and cached in memory for the configured time-to-live (TTL) to minimize API calls while ensuring rotated credentials are picked up promptly.

The following code retrieves the credential from Secrets Manager:

  import boto3 
  secrets_client = boto3.client('secretsmanager') 

  def get_system_credentials(): 
      """Retrieve the system service account credential from Secrets Manager.""" 
      response = secrets_client.get_secret_value( 
          SecretId=os.environ['SYSTEM_CREDS_SECRET_NAME'] 
      ) 
      return json.loads(response['SecretString']) 

IAM permissions: The interceptor’s execution role requires secretsmanager:GetSecretValue scoped to the specific secret Amazon Resource Name (ARN), and kms:Decrypt scoped to the KMS key used to encrypt it. Follow the principle of least privilege by restricting the resource ARN rather than using wildcards.

Note: The agent doesn’t have access to Secrets Manager. Only the request Lambda interceptor—a deterministic function not influenced by model behavior—retrieves credentials. This isolation is designed to mitigate the risk of adversarial prompts instructing the model to access or exfiltrate authentication credentials, even if the agent is compromised.

Step 4: Construct the Basic Auth header

The request Lambda interceptor constructs the Basic Auth header using the system credential retrieved for the downstream tool.

The following code shows the core transformation logic.

  def build_system_auth_header(headers): 
      """Validate JWT and construct Basic Auth header with system credential.""" 
      auth_header = headers.get('Authorization', '') 
      if not auth_header.startswith('Bearer '): 
          return _error_response(401, "No Bearer token found in request.") 

      # Validate JWT (defense-in-depth) 
      claims = validate_jwt(auth_header[7:]) 
      if not claims: 
          return _error_response(401, "JWT validation failed.")
          
      # Retrieve system credential from Secrets Manager 
      creds = get_system_credentials()
      
      # Construct Basic Auth header (RFC 7617) 
      basic_auth_encoded = base64.b64encode( 
          f"{creds['username']}:{creds['password']}".encode() 

      ).decode() 
      headers['Authorization'] = f"Basic {basic_auth_encoded}" 
      return headers 

Conclusion

A request Lambda interceptor in Amazon Bedrock AgentCore Gateway can bridge the gap between the authentication patterns supported by the gateway and the authentication requirements of legacy tool APIs that haven’t yet migrated to modern authentication standards. As demonstrated in this post, the interceptor validates the inbound JWT, retrieves system credentials from Secrets Manager, and constructs the downstream tool’s Basic Auth header without modifying tool schemas or agent implementation.

This approach is an interim integration pattern, not a target architecture. It introduces a credential that must be synchronized between Secrets Manager and the tool’s identity store (such as Active Directory), adding operational overhead for rotation, drift detection, and lifecycle management. The recommended path is to modernize the downstream tool to accept OAuth 2.0, SAML, or OpenID Connect, eliminating stored credentials entirely. Until that modernization is complete, the interceptor isolates credential handling from the agent runtime, designed to help ensure that the agent—a non-deterministic system influenced by user prompts—does not have access to authentication secrets.

If you have feedback about this post, submit comments in the Comments section below.

Nashant Mainro

Nishant Mainro

Nishant is a Senior Security Solutions Architect with Amazon Web Services, based in Atlanta, Georgia. He brings 17+ years of security experience, focusing on securing AI and agentic workloads. He enjoys architecting security controls at scale, including identity, authorization, and data access for AI agents, empowering customers to confidently build generative AI applications and protect their data on AWS.

Author

Ram Ramani

Ram is a technology leader in AI security focusing on AI-driven software development, AI for security, and building secure agents. Ram advises leaders, developers and architects on how to make an organization AI-native and secure while benefiting from velocity provided by AI-driven development.

Security Hub Extended adds Supply Chain Security as its tenth category

Post Syndicated from Michael Fuller original https://aws.amazon.com/blogs/security/security-hub-extended-adds-supply-chain-security-as-its-tenth-category/

Since February, we’ve grown AWS Security Hub Extended from 14 curated partners across 9 categories to 23 partners across 10. At Black Hat this month, 14 of those partners were at the Amazon Web Services (AWS) booth demoing live. Four of those partners delivered theater talks and ten were featured on SecurityLive streaming. We hosted a partner reception that brought our leadership together with partner executives to plan what comes next. These are companies investing real engineering and real go-to-market (GTM) alongside us, and increasingly with each other, because the model resonates with the customers they’re talking to every day. The most common question we heard at the booth was when Supply Chain Security was coming.

It’s here. And that’s the thing I want to spend the most time on today, because it’s the category customers keep asking us about.

Supply Chain Security: The category customers have been asking for

Software supply chain risk has moved from a security-team concern to a board-level conversation. SolarWinds showed what happens when a build system is compromised. Log4j showed what a single transitive dependency vulnerability can do at global scale. The xz utils backdoor showed the patience of a maintainer-compromise attack executed over years. Each demonstrated a different dimension of the same problem, and the pace is accelerating. Attackers know that a fast way into an enterprise is through the open source packages that enterprise unknowingly trust.

Every customer I talked to at Black Hat had this on their risk register. Most still hadn’t operationalized a solution, because doing so meant a standalone deployment, a new contract, a new console, and integration work their security team couldn’t prioritize. That’s the friction we aim to remove.

Security Hub Extended now offers Supply Chain Security with Chainguard and Socket as the curated partners. Supply Chain Security uses the same model as everything else in Extended. Every offering has pay-as-you-go pricing, one bill, no required long-term commitment. For enterprises that prefer to continue using the procurement process they always have, Security Hub Extended Private Offers are also available. These are committed term agreements with deeper discounts, the ability to aggregate spend across partners on a single AWS bill, and both monthly and annual payment options throughout the term. You pick the path that fits how you buy.

What Chainguard does

Chainguard gives you open source dependencies rebuilt from source in a hardened, verified build process, so what enters your environment is malware-resistant and provenance-backed. Their research shows that rebuilding from source would have stopped 98% of known malicious packages from ever reaching production. If you can’t verify the source, it never appears in the Chainguard repository. That’s the filter between the public registry and your developers.

What Socket does

Socket analyzes the actual behavior of open source packages to block malicious dependencies at the time of install. Not after a Common Vulnerability and Exposures (CVE) is published days or weeks later. At the moment the package tries to land in your environment, Socket flags it based on what it does, not what a database says about it. Its reachability analysis then tells you which vulnerabilities are exploitable from your code instead of drowning your team in noise. You pay for the distinct packages you check, not for how often your builds run.

Why they work together

Together, Chainguard and Socket cover the two questions that matter:

  • Can I trust what I’m pulling in?
  • Can I stop malicious components before they get built into my applications?

Chainguard helps secure the foundation your code is built on. Socket secures the packages you pull into it. Both help protect your software supply chain regardless of where you deploy—across clouds or on-premises. Activate both through Security Hub Extended and their findings flow into Security Hub in OCSF (Open Cybersecurity Schema Framework) alongside everything else, so a supply chain risk is correlated and prioritized next to your endpoint, identity, and cloud signals. From there, it routes out to the downstream tools you’ve already integrated, so it fits the pipeline your builders run today.

23 partners, 10 categories. Built on what customers asked for

Every partner in Security Hub Extended is here because customers told us they needed that capability and that specific solution was already working for them. We add categories because the threat landscape evolves, and we add partners because customers point us to who’s solving those problems well. The goal is straightforward: Simplify adopting the security solutions your peers are already succeeding with, through the AWS relationship you already have.

The full set today spans endpoint, identity, email, network, data, browser, cloud, AI, security operations, and now supply chain. The 23 curated partners are 7AI, Britive, Chainguard, CrowdStrike, Cyera, Island, LayerX, Native Security, Noma, Okta, Oligo, Opti, Palo Alto Networks, Proofpoint, SailPoint, SentinelOne, Socket, Splunk, Sublime, Upwind, Varonis, Zenity, and Zscaler.

Our focus now is deepening integrations and reducing activation friction so these solutions work together, not in isolation. That’s where the real value compounds.

What we’re building next

Everything I’ve described so far is the commercial model working: Customers buying best-of-breed security through one AWS relationship with the flexibility they expect. But the bigger vision is the integration layer that makes these tools genuinely better together, not just easier to buy together.

The integration we’re most focused on is cross-partner correlation, turning signals from an endpoint solution, an identity solution, and a cloud solution into one exposure and one attack path instead of three disconnected alerts. Right alongside that, we’re dramatically reducing the activation, deployment, and integration friction so customers go from subscribing to seeing value in hours rather than weeks. Both efforts enable the curated solutions you already trust to deliver stronger outcomes together than they do apart.

That’s the build we’re accelerating with our partners now, and you’ll hear more leading into re:Invent.

Explore what’s available

If you’re running open source in production and don’t yet have supply chain visibility, start there. Activate Chainguard and Socket through the Security Hub console today. If you’re managing multiple security vendor relationships and want to understand what consolidation looks like with Security Hub Extended, talk to your AWS account team. Pricing for every partner is published on our pricing page, no sales call required. And if you’re already using Security Hub for posture management and threat detection, the Extended plan is available in the same console you already use.

We’re just getting started.

If you have feedback about this post, submit comments in the Comments section below.

Michael Fuller

Michael has been with AWS for 16 years and led product for AWS Security Services for 11 years. Michael has 29 years in the industry and held several roles in product management, business development, and software development for IBM, Cisco, and Amazon. Michael has a Bachelor’s of Science in Computer Engineering from the University of Arizona and an MBA from the University of Washington.

Updates to your AWS Sign-In experience

Post Syndicated from Vaibhav Chowla original https://aws.amazon.com/blogs/security/updates-to-your-aws-sign-in-experience/

Amazon Web Services (AWS) is gradually introducing updates to the AWS Sign-In and sign-up experience to a limited number of customers. We’re sharing these changes so you will know what to expect as we gradually make the updated experience available to more customers. These updates include new options for creating and accessing AWS accounts. To support these options and provide a more consistent experience, we’ve redesigned the AWS sign-in page and refreshed the session selection page. While some screens and interactions have changed, existing customers will continue using the same sign-in methods and credentials they use today. If you see a sign-in page that looks different from what you’re used to, this is an expected change.

In this post, we walk through what’s new with screenshots so you’ll know what to expect. If your organization relies on the current sign-in interface for browser automation or scripted workflows, review these updates to understand how they might affect your configuration.

Redesigned Sign-In page

The AWS Sign-In page is getting a new look. Figure 1 shows the current sign-in page, where you choose between Root user and IAM user before entering your sign-in information.

Figure 1: Current AWS sign-in page

Figure 1: Current AWS sign-in page

The redesigned sign-in page, shown in Figure 2, introduces a unified email entry point for signing in to AWS. Root users and customers using the new email-based sign-in method for AWS accounts created with the updated sign-up experience enter their email address and choose Continue. AWS automatically determines the appropriate sign-in flow based on the email address provided.

If you’re signing in as an IAM user, choose IAM User to continue to the IAM User Sign-In page. Enter your account ID or alias, AWS Identity and Access Management (IAM) username, and password to sign in.

Figure 2: Redesigned AWS sign-in page

Figure 2: Redesigned AWS sign-in page

The redesigned page also includes sign-in options for customers whose AWS account was created using a supported identity provider, such as Google, GitHub, Apple, or an Amazon.com account. If you’re an existing AWS customer, continue using the same credentials you use today, and AWS will guide you through the appropriate sign-in experience. Sign-in with a supported identity provider is available only for AWS accounts that were created using that identity provider.

If your organization uses AWS IAM Identity Center or IAM federation to access AWS, continue signing in through your organization’s access portal or federation URL. Your existing sign-in process doesn’t change.

Note: Although you don’t need to take specific actions to benefit from these updates, if your setup depends on the current UI for automated tasks, you might notice changes. For the most reliable and stable experience, use the AWS supported options to grant programmatic access to your users. For more information, see the programmatic access options.

Try the redesigned sign-in experience

Before the redesigned sign-in experience becomes the default, AWS will display a banner on the existing sign-in page inviting you to try it, as shown in Figure 3. Selecting Change to new experience takes you to the updated sign-in flow. The existing experience remains available until the redesigned experience becomes the default.

Note: After you select Change to new experience, you’ll continue to see the redesigned sign-in experience in that browser. To return to the existing experience while it’s still available, clear your browser cookies.

Figure 3: Current AWS sign-in page with the banner to try the redesigned experience

Figure 3: Current AWS sign-in page with the banner to try the redesigned experience

Redesigned session selection experience

AWS supports multiple active account and role sessions, so you can stay signed in to more than one account at a time. We’ve redesigned the AWS session selection page with a refreshed look that simplifies viewing and managing your active sessions. When you return to AWS while you have active account or role sessions, the session selection page displays those sessions in one place, including the account, role, and recent sign-in information to help you identify the session you want to use, as shown in Figure 4.

Figure 4: New session selection page

Figure 4: New session selection page

From this page, you can select an existing session, sign out of one or all sessions, or add another AWS session. Choose Add session to sign in to another AWS account while remaining signed in to your existing sessions.

Conclusion

The redesigned AWS Sign-In and session selection pages provide an updated experience while continuing to support the sign-in methods you use today. If you’re an existing AWS customer, there’s no change to how you sign in to your account. We encourage users who rely on browser automation or other workflows that interact with the sign-in experience to review these updates and ensure their systems are compatible with the redesigned experience.

To learn more, see the AWS Sign-In User Guide. If you have questions or feedback, start a new thread in IAM re:Post or reach out to AWS Support.

Vaibhav Chowla

Vaibhav is a Senior Technical Product Manager at AWS, specializing in AWS Identity products. He focuses on enhancing user authentication and security, helping customers of all sizes solve complex identity and access management challenges. Outside of technology, Vaibhav enjoys traveling and exploring new cultures and cuisines.

Rodney Underkoffler

Ella Segura

Ella Segura is a Principal Product Manager on the AWS Identity Customer Experience team. Based in Austin, TX, she focuses on making security foundations simple and accessible for builders at every stage. Outside of work, she enjoys cooking, reading, building Legos, and traveling to new places.

AWS Certificate Manager will discontinue email validation to prove domain validation for certificates

Post Syndicated from Adam Aboudi original https://aws.amazon.com/blogs/security/aws-certificate-manager-will-discontinue-email-validation-to-prove-domain-validation-for-certificates/

Today, we’re announcing that AWS Certificate Manager (ACM) will discontinue support for email-validated public certificates by September 30, 2027. If you use email validation for your ACM public certificates, you need to migrate to DNS validation before that date. This change aligns with the Certification Authority/Browser (CA/B) Forum’s industry-wide deprecation of email-based domain validation and gives you a full year to migrate ahead of the Forum’s March 2028 deadline.

In this blog post, we share the rationale for this change, the timeline, and the steps you can take to migrate your certificates to DNS validation.

Background

The CA/B Forum sets the standards that browsers and certificate authorities must follow for publicly trusted certificates. In November 2025, they voted to end support for email-based domain validation effective March 15, 2028. After that date, certificates validated through email won’t be trusted by browsers, regardless of which certificate authority issued them.

ACM will be deprecating its email validation in-line with the CA/B Forum’s requirements, by September 30, 2027. The ACM timeline gives customers one year to migrate before the CA/B Forum’s hard deadline.

Timelines for these changes

If you currently use email validation for certificates requested from ACM, there are a few important dates that you should be aware of:

  • January 1, 2027: ACM will no longer offer email validation in new AWS Regions.
  • March 31, 2027: ACM will no longer offer email validation for new certificate requests in any Region.
  • September 30, 2027: ACM will no longer renew existing certificates that use email validation in any Region.
  • March 15, 2028: Per the CA/B Forum, public certificate authorities can no longer use email-based domain validation to issue or renew publicly trusted certificates. Certificates issued before this date remain valid until they expire.

Check for existing email validated certificates

If you have any ACM issued public certificates, you can check whether any of them are email validated by using the AWS Management Console for ACM or the AWS Command Line Interface (AWS CLI).

Identify email validated certificates using the ACM console

Use the following steps in the console to find email validated certificates.

  1. Open the ACM console.
  2. Select the filters Validation method = Email and Type = Amazon Issued for a list of email validated certificates.
  3. Any certificates listed are public email-validated certificates and should be migrated before September 30, 2027.
  4. Figure 1: List of all public email validated certificates

    Figure 1: List of all public email validated certificates

Identify email-validated certificates using the AWS CLI

Use the following commands to find email validated certificates.

# Discover email validated public certificates 
region="${1:-us-east-1}" 

aws acm list-certificates --region "$region" \ 
--query "CertificateSummaryList[?Type=='AMAZON_ISSUED'].CertificateArn" --output text | tr '\t' '\n' | while read -r arn; do aws acm describe-certificate --region "$region" --certificate-arn "$arn" \
--query 'Certificate.[DomainName,Type,DomainValidationOptions[0].ValidationMethod]' \ 
--output text done | awk -F'\t' '$3 == "EMAIL"' | column -t 

Usage: 
chmod +x list-email-validated-certs.sh 
./list-email-validated-certs.sh # default region, us-east-1 
./list-email-validated-certs.sh us-west-2 # another region

Migrate existing email validated certificates

To assist you in this migration, ACM is updating the UpdateCertificateOptions API so you can switch a certificate’s validation method from email to DNS in place. This means the certificate Amazon Resource Name(ARN) will remain the same and no changes will be needed to your AWS resources that reference the certificate.

When you update a certificate to DNS validation, ACM provides a CNAME record to add to your DNS configuration, and you have 72 hours to add that record. During this window, the certificate continues to function normally on email validation. If the 72 hours elapse without a DNS update, the certificate stays active on email validation and you can retry when ready. After DNS validation is complete, ACM is designed to automatically renew your certificate before it expires without further manual intervention required. We recommend completing migration before September 30, 2027, so that ACM can keep your certificates up to date without interruption.

To migrate using the console

  1. After you’ve identified a certificate that needs updating, open it and select Update validation method at the top of the page.
    Figure 2: DNS Validation prompt when viewing an email validated public certificate.

    Figure 2: DNS Validation prompt when viewing an email validated public certificate.

  2. After the update is triggered, you will see a View DNS records flashbar at the top of the certificate page.
    Figure 3: View DNS validation records after updating validation method.

    Figure 3: View DNS validation records after updating validation method.

  3. Select View DNS Records in the flashbar to open a dialog box from which you can download the CSV file for the CNAME records to export to other DNS providers.
    Figure 4: Get DNS validation information from the dialog box

    Figure 4: Get DNS validation information from the dialog box

  4. For Route 53 users, there is a Create records in Route 53 that makes the validation available as a one-click option.
    Figure 5: Create DNS validation records into Route 53

    Figure 5: Create DNS validation records into Route 53

To migrate using the AWS CLI:

For instructions on how to update certificates using the AWS CLI, see the email to DNS migration user guide.

Alternatives after email validation is no longer available

ACM supports two validation methods for new certificates going forward:

  • DNS validation – Add a CNAME record to your DNS configuration. ACM automatically renews DNS-validated certificates as long as the record remains in place. We recommend this method for most use cases.
  • HTTP validation for CloudFront – ACM provides a unique token that you host at a well-known URL path on your domain. This method is only available for certificates used with Amazon CloudFront.

Both methods remove the manual approval step required by email validation and let ACM renew your certificates automatically.

Conclusion

The deprecation of email validation and use of the new UpdateCertificateOptions API helps keep your certificates trusted and your applications running as industry standards evolve. The updated UpdateCertificateOptions API is designed to make this migration straightforward: switch your validation method in place, add the DNS record, and ACM is designed to handle renewals automatically from that point forward.

If you have questions or need assistance migrating, contact AWS Support or start a new thread on the AWS re:Post ACM Forum.

If you have feedback about this post, submit comments in the Comments section below.
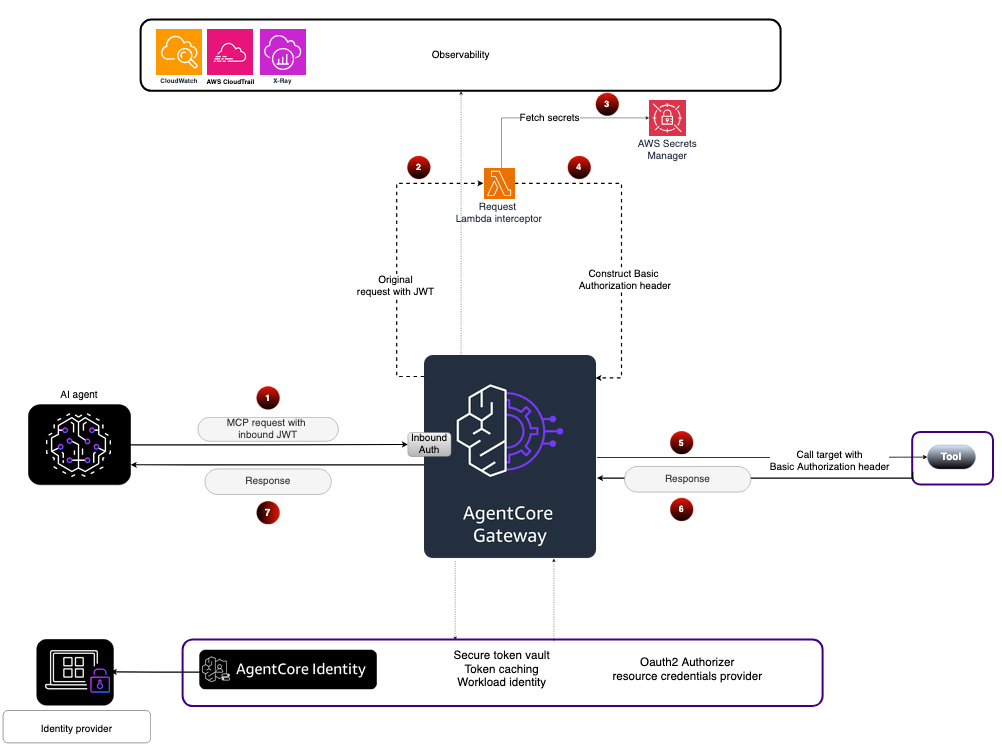

Adam Aboudi

Adam Aboudi

Adam is a Senior Technical Product Manager on the AWS Certificate Manager team. He focuses on helping customers simplify certificate lifecycle management and maintain strong security posture across their AWS environments.

Poojil Tripathi

Poojil Tripathi

Poojil is a Solutions Architect at AWS based out of Austin, TX. They work with AWS customers to help them design secure architectures for all types of workloads. They would like to remind you to dance like no one is watching, but encrypt like everyone is.

How AWS IAM role manager rethinks the starting point for IAM roles

Post Syndicated from Zach Jiang original https://aws.amazon.com/blogs/security/how-aws-iam-role-manager-rethinks-the-starting-point-for-iam-roles/

When you build a new application or capability on Amazon Web Services (AWS), you want to focus on what you’re building. Getting a service running almost always begins with AWS Identity and Access Management (IAM). Many AWS services that act on your behalf need an IAM role, an identity the service assumes to access your resources with a defined set of permissions. You then author a trust policy so the service can assume the role, choose the permissions the workload needs, and attach it. Configuring roles and policies for common patterns is repeatable work that doesn’t need to be manual.

IAM role manager does that work for you. When role manager is enabled, AWS creates and configures the IAM roles as you build in supported service consoles, so you can start using a service and let AWS handle the role behind it. You create the resource you want, and role manager provisions and attaches the role you need as part of the same flow, so you can build now and refine permissions as your workload matures.

With that step automated, getting started takes minutes. You can create an AWS Lambda function and start running your code, with its execution role already created and attached, without switching context to set one up. Role creation becomes an automated part of building your application rather than a separate step.

Role manager is especially useful when you’re getting started: the moments when you want to stand up a service or get a proof of concept running and want to defer role configuration until later in your development process. You don’t need prior IAM experience to get started. You keep full control of what it creates, because the roles are ordinary IAM roles that you can view, edit, or delete like any role you author yourself. When you want to tighten a role, AWS IAM Access Analyzer reviews how it has been used and recommends a policy scoped to only the permissions it needs.

How to enable role manager

Role manager has two states, enabled and disabled. Enabling it for an account authorizes AWS to create roles in that account. In an organization, administrators can use a service control policy (SCP) to control whether member accounts can enable or use role manager. To enable it:

  1. Open the IAM console and choose Account settings.
  2. In the role manager section, choose Enable.
Figure 1: Enable Role Manager

Figure 1: Enable Role Manager

Some AWS services already create a role for you when you create a resource that needs one. Role manager doesn’t change that: those services keep creating roles automatically, and roles you already created keep working. What role manager adds is a single account-level control, and coverage for a case that built-in flows can’t handle: tasks whose permissions AWS can’t determine in advance, such as running your own code. For those tasks, role manager provisions a role that you can narrow later.

Example: Create an Amazon EventBridge rule

Start with a common task: an Amazon EventBridge rule that invokes a target, such as an Amazon Simple Queue Service (Amazon SQS) queue or an Amazon Simple Notification Service (Amazon SNS) topic. Without role manager, you would pause here to create a role that lets EventBridge invoke the target, write the role’s trust policy, attach the required permissions, and then return to finish the rule. With role manager enabled, you define the rule and its target, choose Create, and role manager provisions the role and attaches it for you. The EventBridge console shows the rule created and ready, and you never open the role-creation flow.

Figure 2: Creating an EventBridge rule with no manual role setup

Figure 2: Creating an EventBridge rule with no manual role setup

The role comes from an AWS managed role template: a definition AWS builds and maintains for a specific task, with the trust policy and permissions already worked out. The console calls a new IAM API, AcquireRole, which finds the matching template, provisions the role from it, and returns it to EventBridge. Depending on the service, AcquireRole either creates a new role or reuses one that already fits, so an account does not fill up with duplicate roles for the same task.

Role manager creates the role using your own IAM permissions, not a separate role-manager permission. To provision a new role, you need permission for the actions the template performs: at minimum, you need permissions to create and attach roles. When AcquireRole reuses an existing role instead of creating one, it needs only iam:GetRole and iam:GetRoleTemplateVersion. If you’re missing either of these permissions, the console tells you which one is needed rather than creating the role.

Run code that calls other AWS services

Not every task has a set of permissions AWS can define in advance. When a role runs your own code, such as a Lambda function, AWS has no way of knowing which services that code will call. Role manager covers this case too: create a Lambda function with role manager enabled, and it attaches an execution role that your code can use right away and that you can narrow once you know what the function calls.

Because the permissions your code needs aren’t known up front, role manager attaches the AWS managed policy PowerUserAccess to the role. PowerUserAccess grants access to AWS services so your function can call what it needs. By design, it doesn’t grant permission to manage IAM, AWS Organizations, or account settings. The template also configures the role to trust only the Lambda service.

Figure 3: Create an AWS Lambda function with no manual role setup

Figure 3: Create an AWS Lambda function with no manual role setup

Role manager attaches an execution role, and your function is ready to run. Figure 4 shows the Execution role panel on the function’s Configuration tab, with the role that role manager attached.

Figure 4: Role manager provides a role automatically to an AWS Lambda function

Figure 4: Role manager provides a role automatically to an AWS Lambda function

You can open the role in the IAM console to review its permissions. Figure 5 shows the role’s Permissions tab with the PowerUserAccess policy attached.

Figure 5: Permissions of the role provided by role manager for an AWS Lambda function

Figure 5: Permissions of the role provided by role manager for an AWS Lambda function

You keep full visibility into what role manager creates. Every role it creates records the role template it came from, and both GetRole and ListRoles return that template reference. You can inspect any role in your account and tell which were created by role manager. You read a role’s trust policy and permissions the same way you would for a role you authored, and AWS CloudTrail records each role’s creation.

Refining roles as workloads mature

As your workloads mature, refine the roles that role manager created to follow least privilege. When you’re ready, you can disable role manager and get IAM Access Analyzer unused access analysis at no additional cost for 90 days. Access Analyzer looks at how each role has been used and recommends a policy you can apply that keeps only the permissions the role needs. Start with the roles attached to your most critical workloads and work outward.

Disabling role manager doesn’t disrupt anything already running: your resources keep the roles they have, those roles stay in your account until you change them, and from that point you author new roles yourself, the same as before. If you would rather narrow a single role than the whole account, editing that role removes it from role manager’s control and it becomes a standard customer-managed role, with your changes preserved. In sandbox or development accounts, keeping role manager enabled saves time. For production workloads, disable role manager and refine the roles it created to least privilege before going live.

Conclusion

Role manager automates IAM role setup so you can focus on building from the start. When you enable it, AWS creates and attaches the IAM roles your resources need as you build, so you can start in minutes without prior IAM experience. Because these are IAM roles that you fully control, you keep the same visibility and the same tools you already use. Keep role manager enabled while you build, and refine the roles it created as your workloads mature.

To get started, enable role manager in the IAM console and create a resource in a supported service. To learn more, see IAM role creation and the list of supported services in the IAM User Guide.

If you have feedback about this post, submit comments in the Comments section below.
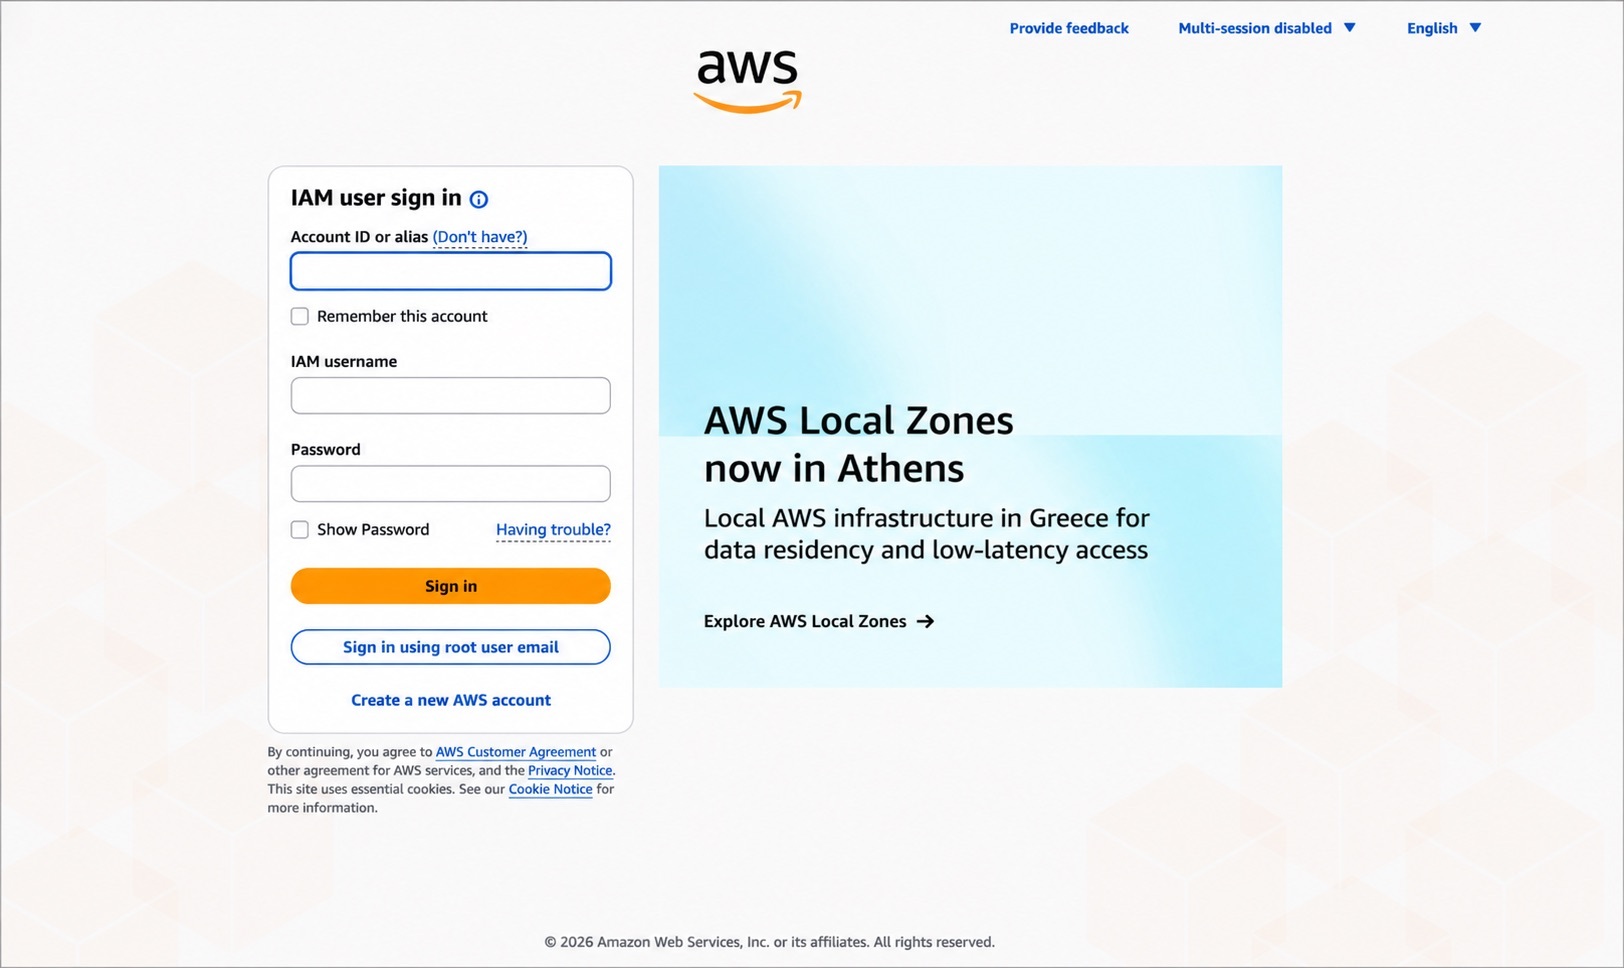

Zach Jiang

Zach Jiang

Zach is a Senior Technical Product Manager at AWS, specializing in AWS Identity products. He focuses on making identity the easy part of building on AWS for customers. Outside of technology, Zach enjoys traveling and exploring new cultures and cuisines.

David Sing

David Sing

David is a Principal Product Manager at AWS, specializing in AWS IAM. He focuses on simplifying IAM for builders and AI agents, safe credential issuance for AI agents, and authorization policy governing agent access. Outside of technology, David enjoys economics and markets, fishing, and time outdoors with his family.

Punit Deotale

Punit Deotale

Punit is a Software Development Manager on the AWS IAM team. He leads work on making it easier for customers to create and manage IAM roles directly within AWS service workflows, so they can set up the right permissions without leaving what they are doing. His focus is reducing permission-setup friction across AWS while helping customers stay aligned with least privilege. Outside of work, Punit enjoys reading, building side projects, and being outdoors.

Landing Zone Accelerator Independent Assessment Report for C5:2020 now available on AWS Artifact

Post Syndicated from Kevin Donohue original https://aws.amazon.com/blogs/security/landing-zone-accelerator-independent-assessment-report-for-c52020-now-available-on-aws-artifact/

Organizations operating in Germany and across Europe increasingly need to demonstrate cloud security compliance under the Cloud Computing Compliance Criteria Catalogue (C5:2020), published by Germany’s Federal Office for Information Security (BSI). Last year, we introduced Landing Zone Accelerator on AWS support for digital sovereignty and today we’re announcing the availability of a new independent assessment report available on AWS Artifact which evaluates how the Landing Zone Accelerator (LZA) on AWS solution provides enhanced coverage for C5:2020 requirements by implementing nearly 200 native security controls. LZA is available using a standard multi-account configuration or as a container-based deployment option in the AWS European Sovereign Cloud, enabling customers with data residency requirements to use the same security configuration baseline.

How this accelerates your compliance journey

Security and compliance are a shared responsibility. LZA takes on part of this responsibility by defining a security architecture baseline and automatically provisioning your AWS environment that scales as your organization grows. Where AWS already provides C5 Type 2 attestation reports for “security of the cloud”, the LZA assessment report offers an independent opinion of how the security baseline LZA provisions aligns with C5:2020 criteria for “security in the cloud”. Instead of starting from scratch, you can deploy with LZA, evaluate the scope of coverage from the report, and use the LZA Compliance Workbook to build on and customize for your organization’s unique use case. These resources can help you reduce time in architecture design, evidence collection, and preparation for C5:2020 assessments. The free LZA Compliance Workbook available on AWS Artifact and open source Universal Configuration GitHub repository are also excellent sources to add to a knowledge base, enabling you to create a security compliance chat agent with Bedrock to assist your governance or assurance teams.

What’s in the report

AWS Partner Schellman, an independent third-party assessor, evaluated the LZA Universal Configuration architecture and security control baseline, which maps to C5:2020 controls in the LZA Compliance Workbook, to determine how the LZA infrastructure aligns to C5:2020 technical requirements. The report concluded that LZA can help implement 325 security controls in aggregate, aligning to technical requirements from eight C5:2020 control areas. It also describes the LZA architecture design, security best practices, and scoping considerations for C5:2020 assessments. This is the first installation of the independent C5 report for LZA, which will be updated in 2027 to evaluate coverage for the pending C5:2026 revision.

In addition to the LZA C5:2020 report, you can also find the LZA Compliance Workbook available on AWS Artifact. It maps C5:2020 requirement identifiers to security implementation statements, giving you a starting point from which you can customize and enhance your compliance documentation for your unique workloads or operational practices after deploying LZA.

Getting started with LZA for C5

  1. Sign in to your AWS account first and then download the LZA C5:2020 Independent Assessment Report and LZA Compliance Workbook from AWS Artifact.
  2. Visit the LZA Universal Configuration GitHub repository to review and download the latest configuration baseline. Also, see guidance for European Sovereign Cloud LZA deployments.
  3. The LZA Implementation Guide walks you through deployment steps, use cases, and pre-deployment considerations.

To learn more, submit a question to a LZA team member or contact your AWS account representative.

If you have feedback about this post, submit comments in the Comments section below.
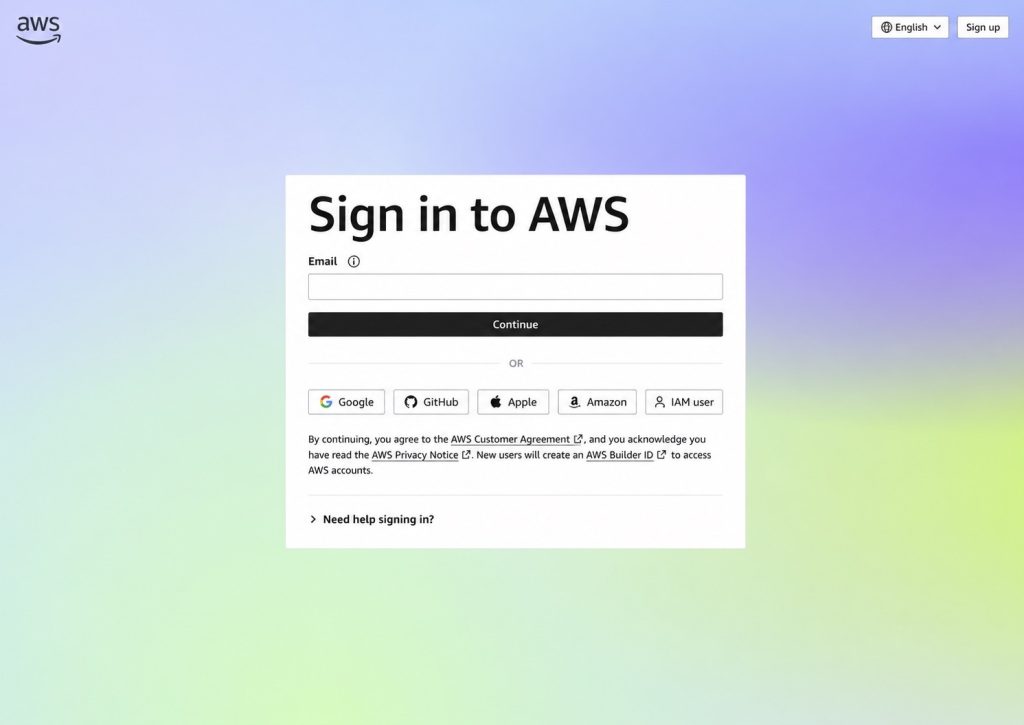

Kevin Donohue

Kevin Donohue

Kevin is a Senior Security Compliance Engineer at AWS, where he builds solutions and resources to help AWS customers achieve their security and compliance goals. Prior to joining the Landing Zone Accelerator team in AWS Professional Services in 2024, Kevin began his tenure with AWS Security in 2019 specializing in FedRAMP compliance and the shared responsibility model.

Michael Wahlers

Michael Wahlers

Michael is a Principal Solutions Architect and Public Sector Specialist working across Germany, Austria, and Switzerland. With passionate enthusiasm, he supports public institutions with innovative digital solutions. His expertise ensures seamless service delivery, making him a valuable asset in shaping the digital future of the public sector. He also enjoys exploring complex distributed systems and incorporating local contexts into his work.

Summer 2026 SOC 1 report is now available with 185 services in scope

Post Syndicated from Baj Bajwa original https://aws.amazon.com/blogs/security/summer-2026-soc-1-report-is-now-available-with-185-services-in-scope/

Amazon Web Services (AWS) is pleased to announce that the Summer 2026 System and Organization Controls (SOC) 1 report is now available. The reports cover 185 services over the 12-month period from July 1, 2025–June 30, 2026, giving customers a full year of assurance. These reports demonstrate our continuous commitment to adhering to the heightened expectations of cloud service providers.

Customers can download the Summer 2026 SOC 1 report through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

AWS strives to continuously bring services into the scope of its compliance programs to help customers meet their architectural and regulatory needs. You can view the current list of services in scope on our Services in Scope page. As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback about SOC compliance.

To learn more about AWS compliance and security programs, see AWS Compliance Programs.


Baj Bajwa

Baj Bajwa

Baj is a Security Assurance Manager at AWS, where he leads the Global Third-Party Assurance product portfolio within the Compliance and Security Assurance (CSA) organization. He has over 15 years of experience in information security, compliance, and risk management, and holds a master’s degree in cybersecurity. Baj maintains CISSP, CISA, PMP, CCSK, GISF, and ICAgile certifications.

Tushar Jain

Tushar Jain
Tushar is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives Tushar holds a Master of Business Administration from Indian Institute of Management Shillong, India and a Bachelor of Technology in electronics and telecommunication engineering from Marathwada University, India. He has over 14 years of experience in information security and holds CISM, CCSK and CSXF certifications.

Michael Murphy

Michael Murphy
Michael is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Michael has over 14 years of experience in information security and holds a master’s degree and a bachelor’s degree in computer engineering from Stevens Institute of Technology. He also holds CISSP, CRISC, CISA, and CISM certifications.

Jeff Cheung

Jeff Cheung
Jeff is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives across business lines. Jeff has Bachelors degrees in Information Systems, and Economics from SUNY Stony Brook, and has over 20 years of experience in information security and assurance. Jeff has held professional certifications such as CISA, CISM, and PCI-QSA.

Logan Moore

Logan Moore
Logan is a Compliance Program Manager at AWS where he leads multiple security and compliance initiatives. Logan has over 10 years of experience in information security and holds a Bachelor’s Degree in Information Systems Management from Virginia Polytechnic Institute and State University.

Noah Miller

Noah Miller
Noah is a Compliance Program Manager at AWS and leads multiple security and privacy initiatives. Noah has 7 years of experience in information security. He has a master’s degree in Cybersecurity Risk Management and a bachelor’s degree in Informatics from Indiana University.

Will Black
Will Black

Will is a Compliance Program Manager at Amazon Web Services where he leads multiple security and compliance initiatives. Will has 10 years of experience in compliance and security assurance and holds a degree in Management Information Systems from Temple University. Additionally, he is a PCI Internal Security Assessor (ISA) for AWS and holds the CCSK and ISO 27001 Lead Implementer certifications.
Ziv Wand
Ziv Wand

Ziv is a Compliance Program Manager at AWS and leads multiple security and privacy initiatives. Ziv has over 6 years of experience in information security assurance, external IT security audits, security control design and implementation, and audit readiness. He holds a Bachelor of Science in Management Information Systems from Binghamton University.
Shalini Mishra
Shalini Mishra

Shalini is a Compliance Program Manager at AWS. She has over 5 years of experience leading end-to-end compliance programs across ISO, SOC, and cloud security frameworks, with deep expertise in third-party risk management and enterprise governance. Shalini holds a Master of Science degree in Information Systems and a CRISC certification.
Patrick Broussard

Patrick Broussard
Patrick is a Security Assurance Analyst at AWS, where he assists with multiple security and privacy initiatives, with expertise in physical security and infrastructure management. He has over 3 years of experience in information security assurance and infrastructure security control operation, and holds a Bachelors of Science from Virginia Polytechnic Institute and State University.

Jimmy Chang

Jimmy Chang
Jimmy is a Security Assurance Analyst at AWS, where he assists with multiple security and privacy initiatives, with expertise in application security and secure software development life cycle. He has over 4 years of experience in information security and holds CISSP and CCSK certifications, and holds a Master of Information Systems Management from Carnegie Mellon University.

Faraz Haq

Faraz Haq
Faraz is a Compliance Program Manager at AWS leading various compliance and security assurance initiatives. Faraz has over 10 years of experience in information security and compliance. He holds Bachelor of Science Degrees in Accounting and Finance from Oakland University.

AWS successfully completed its 2025-26 NHS DSPT assessment

Post Syndicated from Tariro Dongo original https://aws.amazon.com/blogs/security/aws-successfully-completed-its-2025-26-nhs-dspt-assessment/

Amazon Web Services (AWS) is pleased to announce its successful completion of the 2025-26 NHS Data Security and Protection Toolkit (NHS DSPT) assessment audit and achieving a status of Standards Exceeded.

The NHS DSPT is an assessment that allows organizations to measure their performance against the National Data Guardian’s 10 data security standards. All organizations that access NHS patient data and systems are expected to use the toolkit to demonstrate their compliance with safe data security standards. NHS DSPT covers standards regarding Personal Confidential Data, Continuity Planning, IT Protection, and more. AWS undergoes the assessment to provide customers with assurance that we are practicing good data security.

The AWS NHS DSPT assessment status is valid until June 30, 2027, and a certificate that confirms our compliance is available on the NHS England website and in AWS Artifact. AWS Artifact is a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

Security and compliance is a shared responsibility between AWS and the customer. When customers move their computer systems and data to the cloud, security responsibilities are shared between the customer and the cloud service provider. For more information, see the AWS Shared Security Responsibility Model.

To learn more about our compliance and security programs, see AWS Compliance Programs.

As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback.

If you have feedback about this post, submit comments in the Comments section below.
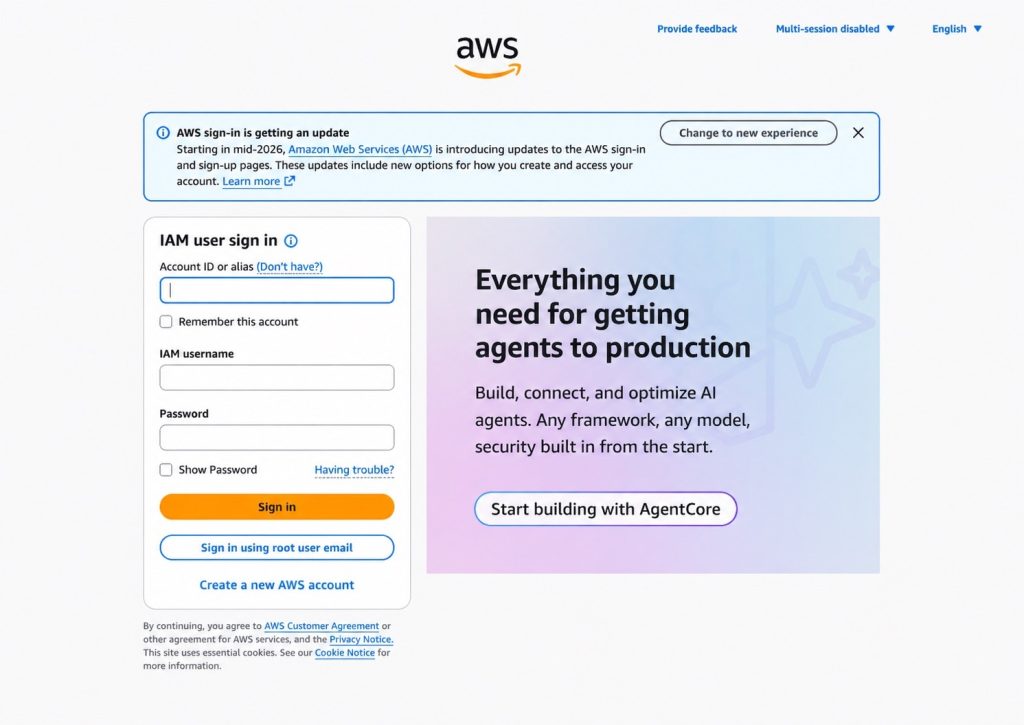

Tari Dongo

Tariro Dongo

Tari is a Security Assurance Program Manager at AWS, based in London. She is responsible for third-party and customer audits, attestations, certifications, and assessments across EMEA. Tari has worked in security assurance and technology risk in the big four and financial services industry for over 15 years.

AWS completes the 2026 Police-Assured Secure Facilities (PASF) audit in Europe (London)

Post Syndicated from Tariro Dongo original https://aws.amazon.com/blogs/security/aws-completes-the-2026-police-assured-secure-facilities-pasf-audit-in-europe-london/

We’re excited to announce that our Europe (London) AWS Region has renewed its accreditation for United Kingdom (UK) Police-Assured Secure Facilities (PASF) for Official-Sensitive data. Since 2017, the Amazon Web Services (AWS) Europe (London) Region has been accredited under the PASF program. This demonstrates our continuous commitment to adhere to the heightened expectations of customers with UK law enforcement workloads. Our UK law enforcement customers who require PASF can continue to run their applications in the PASF-accredited Europe (London) Region in confidence.

The PASF is a long-established assurance process, used by UK law enforcement, as a method for assuring the security of facilities such as data centers or other locations that house critical business applications that process or hold police data. PASF consists of a control set of security requirements, an on-site inspection, and an audit interview with representatives of the facility.

The Police Digital Service (PDS) confirmed the accreditation renewal for AWS on May 28, 2026. A confirmation letter can be found on AWS Artifact. The UK police force and law enforcement organizations can also obtain confirmation of the compliance status of AWS through the Police Digital Service.

To learn more about our compliance and security programs, see AWS Compliance Programs.

As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback.

If you have feedback about this post, submit comments in the Comments section below.
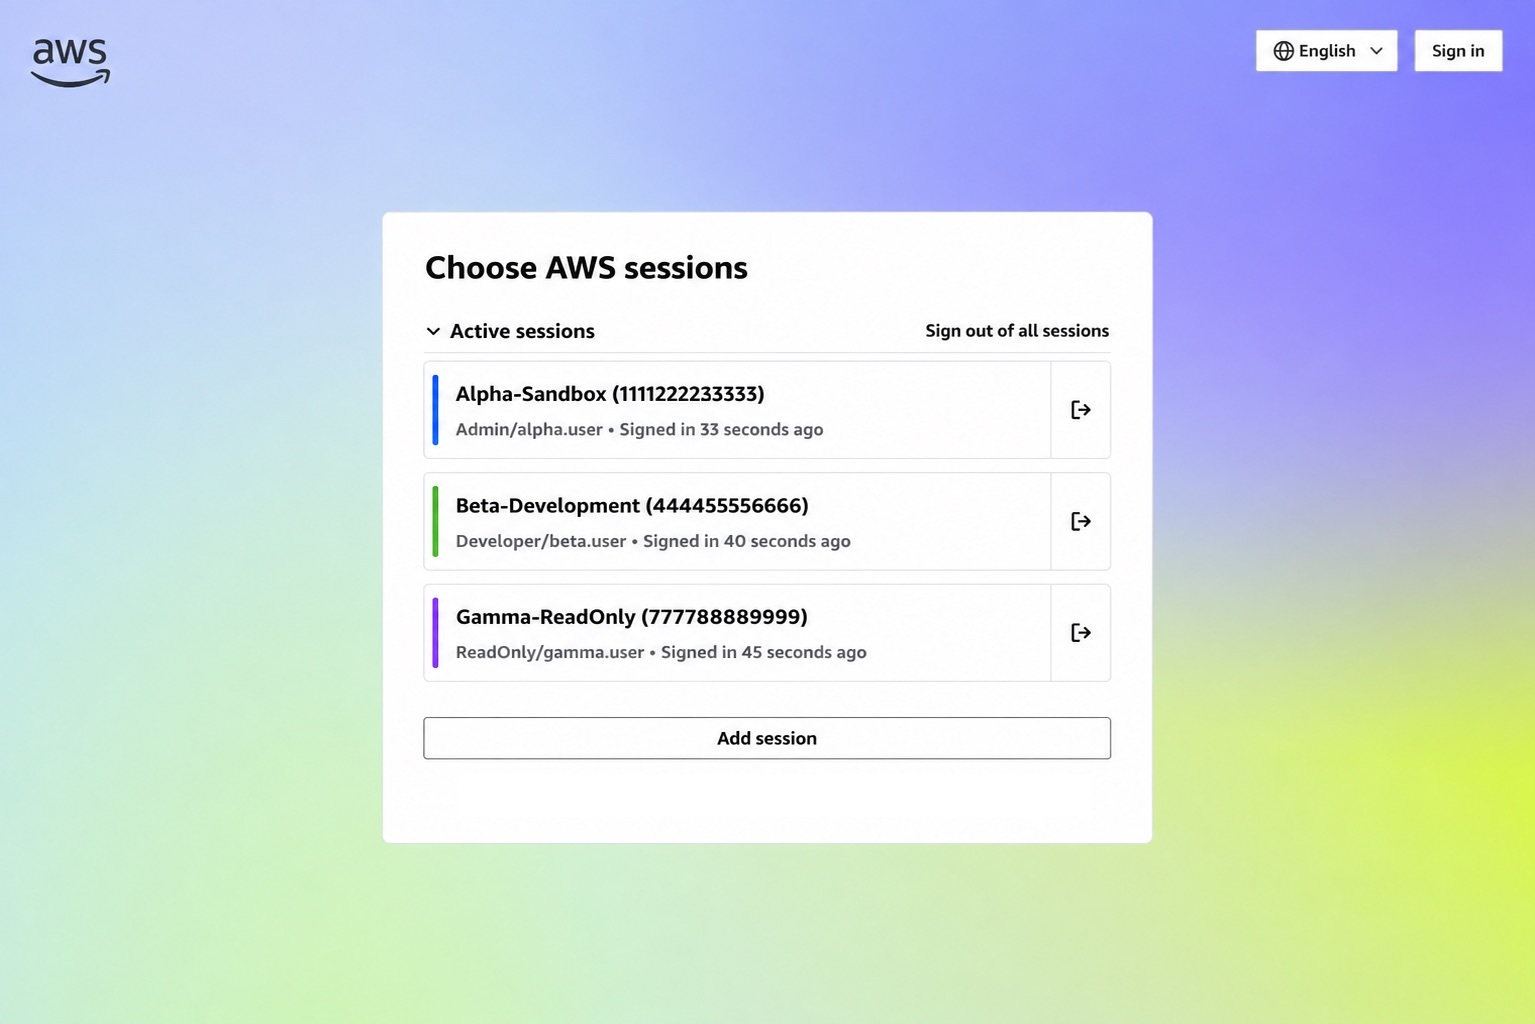

Tari Dongo

Tariro Dongo

Tari is a Security Assurance Program Manager at AWS, based in London. She is responsible for third-party and customer audits, attestations, certifications, and assessments across EMEA. Tari has worked in security assurance and technology risk in the big four and financial services industry for over 15 years.

2026 AWS CyberVadis report now available for due diligence on third-party suppliers

Post Syndicated from Tariro Dongo original https://aws.amazon.com/blogs/security/2026-aws-cybervadis-report-now-available-for-due-diligence-on-third-party-suppliers/

We’re excited to announce that Amazon Web Services (AWS) has completed theCyberVadis assessment of its security posture with the highest score (Mature) in all assessed areas. This demonstrates our continued commitment to meet the heightened expectations for cloud service providers. Customers can now use the 2026 AWS CyberVadis report and scorecard to reduce their supplier due-diligence burden.

With the increasing adoption of cloud products and services across multiple sectors and industries, AWS is a critical component of customers’ third-party environments. Regulated customers, such as those in the financial services sector, are held to high standards by regulators and auditors when it comes to exercising effective due diligence on third parties.

Many customers use third-party risk management services such as CyberVadis to better manage risks from their evolving third-party environments and drive operational efficiencies. In support of these efforts, AWS has completed its annual CyberVadis security posture assessment, conducted by CyberVadis security analysts.

CyberVadis is a comprehensive third-party risk assessment process that combines the speed and scalability of automation with the certainty of analyst validation. CyberVadis assessments employ a dynamic and comprehensive approach to third-party risk assessment, replacing outdated static spreadsheets and the need for annual AWS assessment access requests. This cloud-based solution provides advanced capabilities by integrating AWS responses with analytics and sophisticated risk models to deliver an in-depth view of the security posture of AWS.

CyberVadis’s risk assessment methodology evaluates 20 topics covering the entire cybersecurity life cycle across four phases: Identify, Protect, Detect, and React. These topics include Data Privacy, Access Management, and Infrastructure Security. The assessment criteria are based on international information security standards, including ISO 2700x, NIST Cybersecurity Framework, Cybersecurity for ICS, PCI DSS, NIS2 and GDPR.

Customers can use CyberVadis results to map the assessment of AWS to commonly used industry frameworks and standards to instantly gain visibility into controls coverage.

AWS customers can download the complete 2026 AWS Assessment Report directly through CyberVadis’s portal using their own account, or through AWS Artifact.

To learn more about our other compliance and security programs, see AWS Compliance Programs.

As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback.

If you have feedback about this post, submit comments in the Comments section below.
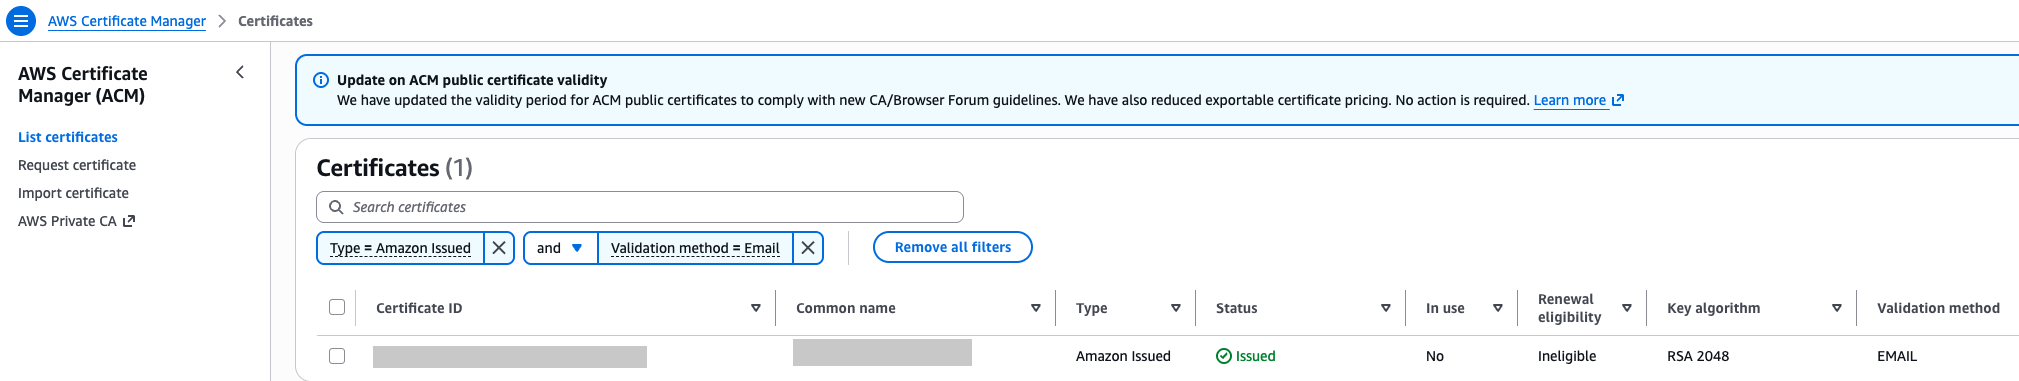

Tari Dongo

Tariro Dongo

Tari is a Security Assurance Program Manager at AWS, based in London. She is responsible for third-party and customer audits, attestations, certifications, and assessments across EMEA. Tari has worked in security assurance and technology risk in the big four and financial services industry for over 15 years.

A decade of enterprise identity in the cloud with AWS Managed Microsoft AD

Post Syndicated from Vladimir Provorov original https://aws.amazon.com/blogs/security/a-decade-of-enterprise-identity-in-the-cloud-with-aws-managed-microsoft-ad/

Ten years ago, we launched AWS Directory Service for Microsoft Active Directory, a fully managed Microsoft Active Directory in the AWS Cloud. In that original announcement, Jeff Barr described a straightforward promise: “You will spend less time administering and more time working on your applications and your business.”

A decade later, AWS Managed Microsoft AD has become the identity backbone for thousands of enterprises worldwide. What started as a way to run directory-aware workloads in the cloud now powers SQL Server authentication, Amazon WorkSpaces virtual desktops, and Amazon FSx for Windows File Server for thousands of enterprises worldwide.

The beginning: Solving a real customer problem

In 2015, customers migrating Windows workloads to Amazon Web Services (AWS) faced a familiar challenge. Microsoft Active Directory (AD) had become the dominant standard for enterprise identity, by some estimates commanding 90% market share for directory services in the Fortune 1000. Running SharePoint, SQL Server, .NET applications, or virtually any Windows workload meant running AD.

However, running AD well comes with significant operational overhead. It requires careful capacity planning, high availability design across multiple sites, ongoing patching and maintenance, backup and disaster recovery procedures, and deep expertise that’s increasingly difficult to find and retain. Customers told us they wanted to focus on their applications, not on managing domain controllers.

So we built AWS Managed Microsoft AD. Powered by actual Windows Server, it delivered real Microsoft AD (not a compatible alternative, but the genuine article) as a fully managed service. We handled the domain controller deployment, the multi-AZ high availability, the automated backups, the patching, the monitoring, and many more features including scalability and multi-Region replication. Customers got a directory they could provision in 25–30 minutes and start using immediately.

From that original What’s New announcement by Bryan Nairn:

“AWS Directory Service now lets you run a Microsoft Active Directory (AD) as a managed service… Host monitoring and recovery, data replication, snapshots, and software updates are automatically configured and managed for you.”

The first decade of innovation

Looking back at the past 10 years, we’re struck by how much AWS Managed Microsoft AD has evolved in response to customer feedback. Here are some of the highlights:

2015: Launch of AWS Managed Microsoft AD (Enterprise Edition) in five AWS Regions, powered by Windows Server 2012 R2. Support for trust relationships with on-premises AD, seamless domain join for Amazon Elastic Compute Cloud (Amazon EC2) instances, and integration with Amazon WorkSpaces.

2017: Introduction of Standard Edition, optimized for small and midsize businesses. This gave customers a cost-effective option for resource forest deployments and smaller workloads.

2018: Added support for schema extensions, enabling customers to extend their directory schema for applications that require custom attributes. Support for Group Managed Service Accounts (gMSA) with Windows containers and other services.

2019: Launched multi-Region replication for Enterprise Edition, allowing customers to automatically replicate their directory across AWS Regions for improved performance and disaster recovery. Added directory sharing across AWS accounts and integration with AWS Organizations.

2020: Introduced fine-grained directory settings for security and compliance, enabling customers to configure secure channel settings for protocols and ciphers. Enhanced compliance support—with the service now HIPAA eligible—included as an in-scope service under PCI DSS, and achieving FedRAMP authorization.

2021: Added CloudWatch metrics for domain controllers, helping customers optimize scaling decisions based on CPU, memory, disk, and AD-specific metrics like DNS and directory read/write operations. Launched integration with AWS Transfer Family for SFTP/FTPS/FTP authentication.

2022: Windows Server 2019 upgrade became available, with customer-initiated updates and automatic migration for all directories beginning in 2023.

2023: AWS Private CA Connector for Active Directory launched, allowing customers to replace self-managed enterprise certificate authorities with AWS Private CA for automatic certificate enrollment to domain-joined objects, with no local agents or proxy servers required.

2024: Launched CRUD APIs for users and groups, enabling IT administrators to manage AD users and groups directly from the AWS Management Console, AWS Command Line Interface (AWS CLI), and APIs, without deploying bastion hosts or opening network ports.

2025: General availability of AWS Managed Microsoft AD (Hybrid Edition), allowing customers to extend their existing AD domain to AWS while retaining administrative control. Introduced self-service edition upgrades through the UpdateDirectorySetup API, eliminating the need for support tickets when scaling from Standard to Enterprise Edition.

2026 and beyond: As we enter our second decade, our roadmap continues to be shaped by the customers who depend on AWS Managed Microsoft AD every day. We’re working on new capabilities driven directly by your feedback, and we look forward to sharing more soon.

Powering identity across AWS

Over the past decade, more than 20 AWS services have added native integration with AWS Managed Microsoft AD. What started with WorkSpaces and EC2 domain join has expanded to more than 20 AWS services, making AWS Managed Microsoft AD foundational for many enterprise customers’ workloads on AWS.

Database services

For many customers, database authentication is a primary driver for adopting AWS Managed Microsoft AD. By pairing Amazon Relational Database Service (Amazon RDS) for SQL Server with AWS Managed Microsoft AD, they gain the benefits of fully managed services while achieving straightforward integration and reduced management overhead. This combination lets developers and DBAs use their existing AD credentials to access SQL Server databases, so they don’t need to manage separate database accounts.

Beyond SQL Server, AWS Managed Microsoft AD enables Windows authentication across the Amazon RDS family:

  • Amazon RDS for Oracle
  • Amazon RDS for PostgreSQL
  • Amazon RDS for MySQL
  • Amazon RDS for DB2
  • Amazon Aurora MySQL
  • Amazon Aurora PostgreSQL

File storage services

Amazon FSx for Windows File Server provides fully managed Windows file shares that integrate natively with AWS Managed Microsoft AD. Customers use AD users and groups to control access to file shares, apply Windows ACLs, and use features like DFS namespaces, all with the same management experience they use on premises.

AWS Storage Gateway supports AD authentication for SMB file shares, enabling hybrid storage architectures where on-premises applications access cloud storage using familiar AD credentials.

AWS Transfer Family added AD integration in 2021, allowing customers to authenticate SFTP, FTPS, and FTP users against their AWS Managed Microsoft AD. This allows customers to migrate file transfer workflows without changing end-user credentials.

End user computing

Amazon end-user computing services were among the first to integrate with AWS Managed Microsoft AD:

Security and identity

AWS IAM Identity Center (formerly AWS Single Sign-On) uses AWS Managed Microsoft AD as an identity source, synchronizing users and groups to provide single sign-on access across AWS accounts and applications. This provides centralized identity management while using your existing AD infrastructure.

AWS Client VPN authenticates users against AWS Managed Microsoft AD, providing secure remote access using corporate credentials.

AWS Management Console access can be federated through AWS Managed Microsoft AD, so AD users can assume AWS Identity and Access Management (IAM) roles and manage AWS resources with their existing credentials.

Compute services

Amazon EC2 instances (both Windows and Linux) support seamless domain join at launch. Windows instances can be managed using Group Policy, and Linux instances can authenticate users through SSSD or Realm integration.

Amazon Elastic Container Service (Amazon ECS) supports AD authentication for Windows containers through Group Managed Service Accounts (gMSA), enabling containerized applications to authenticate to AD-integrated resources.

Business applications

This breadth of integration means customers can standardize on a single directory for their entire AWS environment, from databases to desktops to file servers to analytics.

Choosing the right edition

Over the years, we’ve learned that customers have different needs when it comes to managed AD. Today, AWS Managed Microsoft AD is available in three editions, each designed for specific use cases.

Standard Edition: Basic, cost-effective identity

Standard Edition is optimized for small and midsize businesses, or for enterprises deploying a resource forest model in a single AWS Region. With 1 GB of directory object storage supporting up to 30,000 objects (approximately 5,000 users), Standard Edition provides everything needed to run directory-aware workloads without the overhead of managing domain controllers.

Common use cases:

  • Resource forest deployments – Many customers use Standard Edition as a resource forest, establishing a trust relationship with their on-premises AD. User identities remain in the customer’s existing domain, while the resource forest manages AWS resources like Amazon RDS for SQL Server and FSx for Windows File Server.
  • Development and test environments – Cost-effective option for non-production workloads
  • Single-Region applications – Workloads that don’t require global presence

Standard Edition is a great starting point, and customers aren’t locked in. With our new self-service upgrade capability (launched October 2025), you can upgrade to Enterprise Edition programmatically through the UpdateDirectorySetup API, no support tickets or maintenance window coordination required.

Enterprise Edition: Built for global scale

Enterprise Edition is designed for organizations with larger user populations, complex deployments, or global footprints. With 17 GB of storage supporting up to 500,000 directory objects, Enterprise Edition provides the capacity and capabilities that large enterprises require.

Key capabilities:

  • Multi-Region replication – Automatically replicate your directory across AWS Regions. Users and applications connect to local domain controllers, reducing latency and providing disaster recovery capabilities.
  • Extended directory sharing – Share your directory with up to 500 AWS accounts, enabling centralized identity across large organizations using AWS Organizations.
  • Higher compute capacity – Larger domain controller instances with more CPU and memory for demanding workloads

If you have users and applications in multiple geographic regions, or anticipate significant growth in directory objects, Enterprise Edition is the right choice.

Hybrid Edition: Extend your existing domain

Launched earlier this year, Hybrid Edition takes a fundamentally different approach. Instead of creating a new AD domain in AWS, Hybrid Edition extends your existing AD domain into the cloud.

What makes Hybrid Edition unique:

  • Same domain – AWS Managed Microsoft AD domain controllers join your existing AD. No new domain name, no trust relationships to configure.
  • Retain administrative control – Unlike Standard and Enterprise where you receive delegated OU permissions, Hybrid Edition preserves your existing administrative rights. Your AD administrators continue using familiar tools while changes replicate to AWS in real time.
  • Preserve existing investments – Security principals, group policies, and permissions transfer seamlessly. No migration of identities required.

Hybrid Edition is ideal for customers who want the operational benefits of AWS-managed domain controller infrastructure without changing their AD architecture or giving up administrative control.

Which edition should you choose?

Use the following table to determine which edition best fits your use case.

Use case Edition
A new AD domain for AWS workloads in a single Region Standard Edition
A resource forest with trust to on-premises AD Standard Edition
Multi-Region replication for global deployments Enterprise Edition
Support for more than 30,000 directory objects Enterprise Edition
To extend your existing AD domain to AWS Hybrid Edition
To retain full administrative control over your AD Hybrid Edition

What we’ve learned: Design decisions that stood the test of time

Looking back at the decisions we made in 2015, several have proven foundational to the service’s success:

  • High availability by default – Every AWS Managed Microsoft AD directory deploys with a minimum of two domain controllers across separate Availability Zones. Customers don’t need to design high availability (HA) architecture, it’s built in.
  • Real Microsoft AD – We chose to run actual Windows Server AD, not a compatible alternative. This means standard AD administration tools work, existing scripts and automation work, and applications that depend on specific AD behaviors typically work without modification.
  • Seamless integration with AWS services – By building native integrations between AWS Managed Microsoft AD and other AWS services, we’ve made it possible for customers to use a single directory across their entire AWS environment.
  • Customer retains control – While AWS manages the infrastructure, customers manage their directory content. You control your users, groups, OUs, and policies using familiar tools.
  • Room to grow – The edition model (and now self-service upgrades) means customers can start with what they need today and scale as requirements evolve.

Looking ahead: The next chapter

As we celebrate 10 years of AWS Managed Microsoft AD, we’re excited about what’s ahead. The launch of Hybrid Edition earlier this year represents a significant expansion of what’s possible, giving customers new flexibility in how they architect their identity infrastructure for hybrid and multi-cloud environments.

We continue to listen to customer feedback and invest in capabilities that reduce operational burden while expanding what you can build. Whether you’re running your first SQL Server database in the cloud, deploying virtual desktops to a global workforce, or modernizing legacy applications that depend on AD, AWS Managed Microsoft AD is here to help.

Thank you to all the customers who have trusted us with their identity infrastructure over the past decade. Your feedback has shaped this service, and we’re committed to continuing to earn that trust for the next 10 years and beyond.

Resources

Ready to get started or learn more? Here are some resources:

If you have feedback about this post, submit comments in the Comments section below.
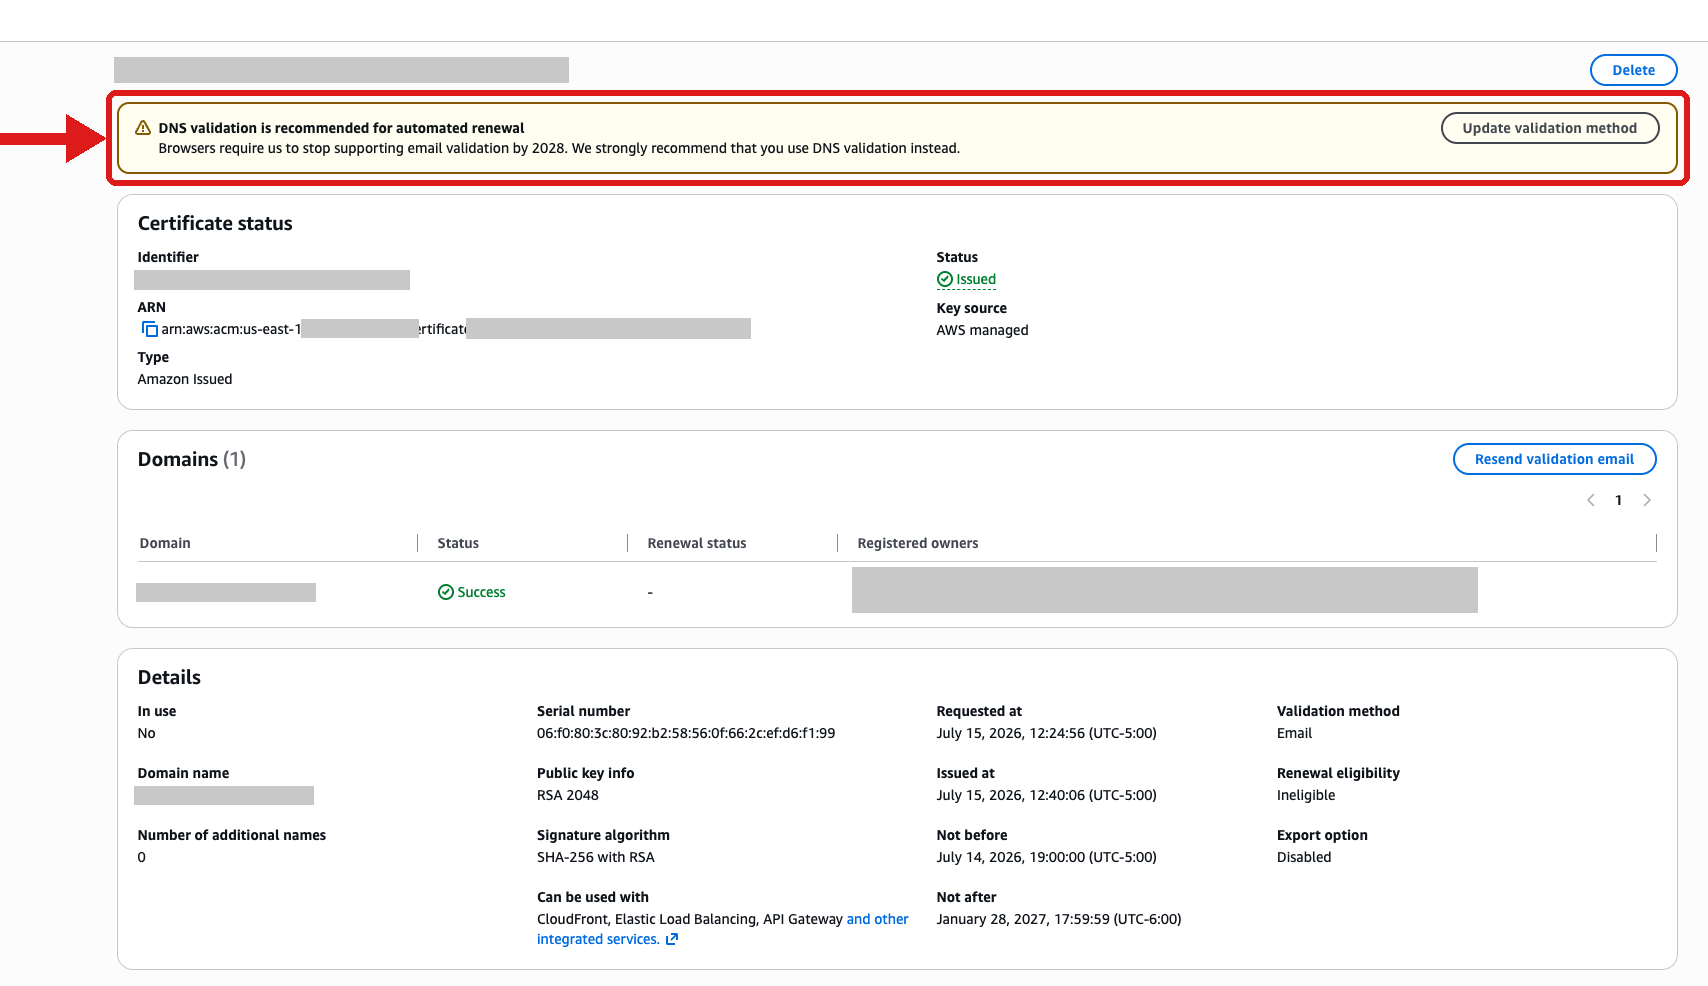

Vladimir Provorov

Vladimir is a Product Solutions Architect from AWS Identity focused on Workforce Identity and Directory Service. He works on developing new features to make Enterprise Identity simpler and more scalable. He is excited to travel and explore the world with his family.

Rodney Underkoffler

Rodney Underkoffler

Rodney is a Senior Solutions Architect at Amazon Web Services, focused on guiding enterprise customers on their cloud journey. He has a background in infrastructure, security, and IT business practices. He is passionate about technology and enjoys building and exploring new solutions and methodologies.

Author

Tekena Orugbani

Tekena is a Sr. Specialist Solutions Architect at Amazon Web Services and a technologist of over 20 years, specializing in Microsoft technologies. At AWS, Tekena is focused on helping customers architect, migrate and modernize their Microsoft workloads on the AWS Cloud. Outside work, he enjoys hanging out with his family and watching soccer.

Securing your Amazon S3 buckets: Identifying and remediating over-permissioned access

Post Syndicated from Hetal Kolekar original https://aws.amazon.com/blogs/security/securing-your-amazon-s3-buckets-identifying-and-remediating-over-permissioned-access/

Misconfigured Amazon Simple Storage Service (Amazon S3) buckets can expose your data to unauthorized access. Without proactive review, S3 bucket policies or Access Control Lists (ACLs) configured with broad access may go unnoticed in your environment. In this post, you learn how to identify and fix over-permissioned S3 buckets across your AWS environment, along with best practice recommendations and automation opportunities to help you prevent security gaps. This post provides a workflow framework and methodology recommendations for your security team to adapt. The focus of this post is on the what and why rather than a prescriptive implementation. You will need to customize the approach based on your organization’s requirements and existing security tooling.

This solution is intended for security engineers, cloud architects, and DevOps teams managing single- or multiple-account AWS environments with Amazon S3 workloads that require access management.

Prerequisites

Before you begin, make sure you have the following in place:

Solution overview

This solution uses a five-phase workflow diagram to detect, remediate, and continuously monitor over-permissioned S3 buckets across your AWS accounts. The following workflow diagram illustrates the high-level end-to-end process for identifying and remediating over-permissioned S3 buckets across your Amazon Web Services (AWS) environment.

Figure 1: Amazon S3 over-permissive access – Detection, remediation, monitoring and cleanup workflow

Figure 1: Amazon S3 over-permissive access – Detection, remediation, monitoring and cleanup workflow

The diagram in Figure 1 consists of five phases:

  1. Setup and prerequisites – Configure AWS Organizations or multi-account access, designate a central security account, deploy AWS Config across all accounts, and enable AWS Security Hub with a central administrator.
  2. Detection and identification – Deploy AWS Config rules (such as s3-bucket-public-read-prohibited and s3-bucket-public-write-prohibited) and run an audit Lambda function that scans each S3 bucket. The function checks three areas: Public Access Block configuration, bucket policy status, and bucket ACL grants. Buckets with issues are added to a risky buckets list. The function then generates a report in CSV and JSON format, uploads it to an output S3 bucket, and sends an SNS alert.
  3. Remediation – Address findings using one or more approaches – Apply restrictive bucket policies to deny public read/write access and restrict access to specific IAM principals; deploy a remediation Lambda function to automatically update bucket policies and disable public access settings; or use CloudFormation StackSets to deploy standardized policies across multiple accounts.
  4. Continuous monitoring – Schedule the audit Lambda function for recurring scans (daily or weekly) using Amazon EventBridge. Use EventBridge to detect policy changes, configure automated notifications for new violations, enable IAM Access Analyzer for S3 to identify external access, and run regular compliance scans.
  5. Resource cleanup – Review and delete resources created during the audit that are no longer needed, including Lambda functions and IAM roles, EventBridge rules, SNS topics and subscriptions, audit output S3 buckets, AWS Config rules, and Security Hub (if enabled only for this audit).

Cost considerations

This section covers the AWS services used in this solution and their associated costs so you can estimate spend before deployment. The primary cost drivers are AWS Config and Security Hub, which scale with the number of accounts and resources you monitor. Lambda, Amazon EventBridge, Amazon SNS, and Amazon S3 typically add minimal costs for most environments. Start with a pilot in one or two accounts to validate costs before scaling.

  • AWS Config – Charges per configuration item recorded and per rule evaluation. Costs scale with the number of accounts and resources tracked.
  • Security Hub – Charges per account per AWS Region for security checks and finding ingestion.
  • Lambda – Charges per request and per GB-second of compute time.
  • EventBridge – Scheduled rules are free. Custom event bus usage might incur charges.
  • Amazon SNS – Charges per notification delivered.
  • Amazon S3 – Storage costs for audit report output files. Minimal for most environments.
  • AWS IAM Access Analyzer – Check the AWS IAM Access Analyzer pricing page to understand which features have costs associated with them.

Check the service pricing pages for current rates. Use the AWS Pricing Calculator to estimate costs for your specific environment before enabling services across all accounts. Consider starting with a pilot in one or two accounts to validate costs before scaling.

Detect and report over-permissioned buckets

This section walks you through setting up the audit environment, deploying the Lambda-based scanner, and generating reports of over-permissioned S3 buckets across your accounts. Follow these steps to identify over-permissioned S3 buckets in your multi-account environment, starting with preparing your environment for an Amazon S3 audit.

To set up the multi-account audit environment:

  1. Set up AWS Organizations or multi-account access. Set up centralized management of your AWS accounts using AWS Organizations or configure cross-account IAM roles.
  2. Choose a central security account. Choose one account as your security/audit account. This account will run the audit Lambda function and collect results from member accounts.
  3. Create an Amazon SNS topic for alerts. Subscribe your security team to receive notifications when over-permissioned buckets are detected. Note the topic Amazon Resource Name (ARN) from the output—you will need it when creating the Lambda execution role (step 6) and the Lambda function (step 9). Confirm the email subscription before testing; Amazon SNS doesn’t deliver alerts until the subscription is confirmed. Learn more in the Amazon SNS Developer Guide.
  4. (Optional): Create an S3 bucket for audit reports. If you plan to use Script v2 for historical reporting and trend analysis, create a dedicated bucket now. Skip this step if you only need real-time alerts using Script v1.
  5. Plan cross-account IAM roles. The central security account needs permission to scan member accounts. Design cross-account roles that:
    1. Grant minimum Amazon S3 read permissions (list buckets, read policies, ACLs, public access configurations).
    2. Include an external ID condition to mitigate the confused deputy problem.
    3. Can be deployed consistently using AWS CloudFormation StackSets.
    4. See the IAM documentation on creating cross-account roles, The confused deputy problem, and IAM security best practices for additional guidance on role configuration and trust policies.

      Note: The specific trust policy and permissions policy for your cross-account roles will depend on organizational requirements. Work with your IAM administrators to grant minimum necessary access for the audit function.

  6. Create the Lambda execution role. Create an IAM role for your Lambda function with the permissions it needs to scan buckets, publish alerts, and write logs. Apply the principle of least privilege—grant only the minimum Amazon S3 read permissions required for the audit (such as, listing buckets, reading bucket policies, ACLs, and public access block configurations), Amazon SNS publish permission for the alert topic created in step 3, Amazon S3 write permission for the output bucket created in step 4 (Script v2), and Amazon CloudWatch Logs permissions. For multi-account scanning, also include sts:AssumeRolepermission for the cross-account role ARNs created in step 5. The AWS Lambda execution role documentation has instructions on creating and configuring execution roles.
  7. To deploy the S3 audit solution Deploy the audit components
    1. Enable AWS Config in member accounts. AWS Config provides compliance monitoring and can detect when S3 buckets are created or modified with public access settings. This will enable the Lambda-based audit to receive real-time detection between scheduled scans. The AWS Config Developer Guide has setup instructions. Deploy pre-defined AWS Config rules to identify overly permissive settings. These managed rules provide automated compliance checking. When AWS Config detects violations, it sends findings to Security Hub (configured in step 8) for centralized visibility alongside the Lambda audit results.
      • s3-bucket-public-read-prohibited
      • s3-bucket-public-write-prohibited
      • Create AWS Config rules for specific permission patterns. For the full list of available rules, see the AWS Config managed rules reference
  8. Enable Security Hub for centralized visibility. Enable AWS Security Hub in member accounts and configure the central security account as the administrator. Security Hub aggregates findings from AWS Config rules (step 7), IAM Access Analyzer (enabled later), and can receive custom findings from your Lambda audit function, providing a single dashboard for Amazon S3 security issues across your organization. See the Security Hub User Guide for setup details.
  9. Deploy the audit Lambda function. Deploy a Python Lambda function using the Boto3 library to list S3 buckets, check their policies, ACLs, and IAM permissions, and identify over-permissioned buckets. See the example scripts that follow.

Important: These code examples aren’t production ready. Adapt them to meet your organization’s requirements and test them in a non-production environment before deployment.

Choose your approach:

  • Script v1 – Best for immediate SNS alerts when issues are detected.
  • Script v2 – Best for historical reports, trend analysis using BI tools.
  • Both scripts – Best for different schedules and ongoing needs.

Audit Lambda function – Example script v1 (Scan and alert)

The following is an example of a Lambda function script for reference purposes. Review, adapt, and test before use in your environment, it scans all S3 buckets in the current account and checks for:

  • Public Access block configuration gaps
  • Bucket policies that allow public access
  • ACL grants to AllUsers

Note: Replace placeholder values with actual values before deployment:

  • <REGION>– Your AWS Region (for example, us-east-1)
  • <ACCOUNT_ID>– Your 12-digit AWS account ID
  • <TOPIC_NAME>– The name of your SNS topic created in step 3
import boto3
import json

def lambda_handler(event, context):
    s3 = boto3.client('s3')
    sns = boto3.client('sns')
    risky_buckets = []
    errors = []

    try:
        buckets = s3.list_buckets()['Buckets']
    except Exception as e:
        return {'statusCode': 500, 'body': f'Failed to list buckets: {str(e)}'}

    for bucket in buckets:
        bucket_name = bucket['Name']
        issues = []

        try:
            # Check Public Access Block — all four settings should be enabled
            try:
                pab = s3.get_public_access_block(Bucket=bucket_name)
                config = pab['PublicAccessBlockConfiguration']
                if not all([
                    config.get('BlockPublicAcls'),      # Block new public ACLs
                    config.get('BlockPublicPolicy'),     # Block new public bucket policies
                    config.get('IgnorePublicAcls'),      # Ignore existing public ACLs
                    config.get('RestrictPublicBuckets')   # Restrict access to public buckets
                ]):
                    issues.append('Public Access Block not fully enabled')
            except s3.exceptions.NoSuchPublicAccessBlockConfiguration:
                issues.append('No Public Access Block configured')

            # Check bucket policy — flag if policy status is public
            try:
                policy_status = s3.get_bucket_policy_status(Bucket=bucket_name)
                if policy_status['PolicyStatus']['IsPublic']:
                    issues.append('Bucket policy allows public access')
            except s3.exceptions.NoSuchBucketPolicy:
                pass  # No bucket policy is acceptable

            # Check bucket ACL
            acl = s3.get_bucket_acl(Bucket=bucket_name)
            for grant in acl.get('Grants', []):
                grantee = grant.get('Grantee', {})
                uri = grantee.get('URI', '')
                # 'AllUsers' = anonymous public access
                # 'AuthenticatedUsers' = any AWS account (still overly permissive)
                if grantee.get('Type') == 'Group' and ('AllUsers' in uri or 'AuthenticatedUsers' in uri):
                    issues.append('Bucket ACL grants public access')
                    break

            if issues:
                risky_buckets.append({'bucket': bucket_name, 'issues': issues})

        except Exception as e:
            errors.append(f'{bucket_name}: {str(e)}')

    # Send alert if risky buckets found
    if risky_buckets:
        message = f'Found {len(risky_buckets)} buckets with public access:\n\n'
        for item in risky_buckets:
            message += f"  {item['bucket']}: {', '.join(item['issues'])}\n"

        sns.publish(
            TopicArn='arn:aws:sns:<REGION>:<ACCOUNT_ID>:<TOPIC_NAME>',
            Subject='S3 Public Access Alert',
            Message=message
        )

    return {
        'statusCode': 200,
        'body': json.dumps({
            'risky_buckets': risky_buckets,
            'errors': errors,
            'total_checked': len(buckets)
        })
    }

Multi-account scanning: This script scans the current account only. To scan across member accounts, see the Multi-account extension section later in this post.

Audit Lambda function – Example script v2 (CSV and JSON report)

The following is an example Lambda function script for reference purposes. Before deploying any script, review error handling, logging, output structure, and permissions. This script generates CSV and JSON output files and uploads them to an S3 bucket for reporting and business intelligence (BI) dashboard integration.

You can deploy both functions with different EventBridge schedules, for example, Script v1 daily for alerts and Script v2 weekly for reports.

Note: Before you deploy this script, replace <OUTPUT_BUCKET_NAME> with the S3 bucket you created for audit reports in step 4.

import boto3
import csv
import json
import os

def lambda_handler(event, context):
    s3 = boto3.client('s3')
    buckets = s3.list_buckets()['Buckets']

    full_access_buckets = []
    for bucket in buckets:
        bucket_name = bucket['Name']
        try:
            bucket_policy = s3.get_bucket_policy(Bucket=bucket_name)['Policy']
            policy = json.loads(bucket_policy)
            for statement in policy['Statement']:
                if (statement['Effect'] == 'Allow'
                    and statement['Principal'] == '*'
                    and 'Action' in statement
                    and 's3:*' in statement['Action']):
                    full_access_buckets.append({'BucketName': bucket_name})
                    break
        except s3.exceptions.ClientError as e:
            if e.response['Error']['Code'] != 'NoSuchBucketPolicy':
                print(f'Error checking bucket policy for {bucket_name}: {e}')

    # Output CSV
    csv_output = os.path.join('/tmp', 'full_access_buckets.csv')
    with open(csv_output, 'w', newline='') as csvfile:
        writer = csv.DictWriter(csvfile, fieldnames=['BucketName'])
        writer.writeheader()
        writer.writerows(full_access_buckets)

    # Output JSON
    json_output = os.path.join('/tmp', 'full_access_buckets.json')
    with open(json_output, 'w') as jsonfile:
        json.dump(full_access_buckets, jsonfile, indent=2)

    # Upload to Amazon S3
    output_bucket = '<OUTPUT_BUCKET_NAME>'
    s3.upload_file(csv_output, output_bucket, 'full_access_buckets.csv')
    s3.upload_file(json_output, output_bucket, 'full_access_buckets.json')

    return {
        'statusCode': 200,
        'body': json.dumps(f'CSV and JSON files uploaded to {output_bucket}')
    }

Important: If this function runs on a schedule, consider implementing a file naming strategy with timestamps to prevent overwriting previous reports or establish a lifecycle policy to manage retention. Include the output bucket in your cleanup procedures when the auditing process is no longer needed.

What if no over-permissioned buckets are found?

If the audit scan returns zero risky buckets, document the clean baseline for future comparison and move to the verification and monitoring phase to so new buckets or policy changes don’t introduce risk over time.

Multi-account extension

The preceding example scripts scan buckets in the current account only. To scan across member accounts in your organization, add the following AssumeRole logic. This function assumes the cross-account IAM role you created during setup, then returns an Amazon S3 client with temporary credentials for each member account.

Note: Before you deploy, configure the following Lambda environment variables:

  • <MEMBER_ACCOUNTS> – Comma-separated list of 12-digit account IDs to scan (for example, 111111111111,222222222222)
  • <CROSS_ACCOUNT_ROLE_NAME> – The IAM role name created in each member account (for example, S3AuditRole)
  • <EXTERNAL_ID> – The external ID configured in the trust policy (for example, s3-audit-external-id)
import boto3
import os

def get_member_s3_clients():
    """
    Assumes the cross-account audit role in each member account
    and returns a list of (account_id, s3_client) tuples.
    """
    sts = boto3.client('sts')
    member_accounts = os.environ.get('<MEMBER_ACCOUNTS>', '').split(',')
    cross_account_role_name = os.environ.get('<CROSS_ACCOUNT_ROLE_NAME>')
    external_id = os.environ.get('<EXTERNAL_ID>')

    clients = []
    for account_id in member_accounts:
        account_id = account_id.strip()
        if not account_id:
            continue

        try:
            assumed_role = sts.assume_role(
                RoleArn=f'arn:aws:iam::{account_id}:role/{cross_account_role_name}',
                RoleSessionName='S3AuditSession',
                ExternalId=external_id
            )

            # Create S3 client with assumed credentials
            s3_client = boto3.client(
                's3',
                aws_access_key_id=assumed_role['Credentials']['AccessKeyId'],
                aws_secret_access_key=assumed_role['Credentials']['SecretAccessKey'],
                aws_session_token=assumed_role['Credentials']['SessionToken']
            )
            clients.append((account_id, s3_client))

        except Exception as e:
            print(f'Failed to assume role in account {account_id}: {e}')

    return clients

To scan each member account, replace the single-account s3.list_buckets() call with a loop over member accounts:

def lambda_handler(event, context):
    all_risky_buckets = []
    all_errors = []

    # Scan each member account
    for account_id, s3_client in get_member_s3_clients():
        try:
            buckets = s3_client.list_buckets()['Buckets']
            for bucket in buckets:
                # ... same scanning logic as the single-account scripts ...
                # Use s3_client instead of s3 for each API call
                pass
        except Exception as e:
            all_errors.append(f'Account {account_id}: {e}')

    # ... same alerting/reporting logic ...

The Lambda execution role in the central security account needs sts:AssumeRole permission for the cross-account role ARNs. Add this to the execution role policy you created in step 5.

Remediate elevated access

This section describes how to fix over-permissioned buckets using account-level controls, bucket policies, and optional automation. Any elevated access that you find needs to be remediated.

Enable Amazon S3 Block Public Access (account level)

Before applying individual bucket policies, enable Amazon S3 Block Public Access at the account level. This prevents buckets in the account from being made public, regardless of individual bucket policies or ACLs. See theS3 Block Public Access documentation for configuration details. See the following example AWS CLI command; replace <ACCOUNT_ID> with the ID of the account you’re using to manage resource access:

aws s3control put-public-access-block \
  --account-id <ACCOUNT_ID> \
  --public-access-block-configuration \
BlockPublicAcls=true,IgnorePublicAcls=true,BlockPublicPolicy=true,RestrictPublicBuckets=true

For multi-account environments, deploy this setting across member accounts using AWS CloudFormation StackSets or AWS Organizations service control policies (SCPs).

Important: Before enabling account-level S3 Block Public Access, check whether any workloads need public bucket access (for example, static website hosting, public dataset sharing). Coordinate with your application teams to identify any exceptions.

Remediate using bucket policies

Implement bucket policies that restrict access to specific IAM users, roles, or accounts. When crafting policies, apply the principle of least privilege and include only the actions and principals required for your use case.

Example S3 bucket policy: deny public read/write access. Modify the resource ARN, actions, and conditions to match your requirements:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Deny",
      "Principal": "*",
      "Action": [
        "s3:PutObject", "s3:PutObjectAcl",
        "s3:GetObject", "s3:GetObjectAcl",
        "s3:DeleteObject"
      ],
      "Resource": "arn:aws:s3:::<BUCKET_NAME>/*",
      "Condition": {
        "StringEquals": {
          "s3:x-amz-acl": ["public-read", "public-read-write"]
        }
      }
    }
  ]
}

Example S3 bucket policy: restrict access to specific IAM principals. Replace <ACCOUNT_ID>, <USERNAME>, and <ROLE_NAME>:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowObjectAccess",
      "Effect": "Allow",
      "Principal": {
        "AWS": [
          "arn:aws:iam::<ACCOUNT_ID>:user/<USERNAME>",
          "arn:aws:iam::<ACCOUNT_ID>:role/<ROLE_NAME>"
        ]
      },
      "Action": ["s3:GetObject", "s3:PutObject", "s3:DeleteObject"],
      "Resource": "arn:aws:s3:::<BUCKET_NAME>/*"
    },
    {
      "Sid": "AllowBucketAccess",
      "Effect": "Allow",
      "Principal": {
        "AWS": [
          "arn:aws:iam::<ACCOUNT_ID>:user/<USERNAME>",
          "arn:aws:iam::<ACCOUNT_ID>:role/<ROLE_NAME>"
        ]
      },
      "Action": ["s3:ListBucket", "s3:GetBucketLocation"],
      "Resource": "arn:aws:s3:::<BUCKET_NAME>"
    }
  ]
}

See the Amazon S3 bucket policy documentation for additional examples and guidance.

Automate remediation with Lambda or CloudFormation StackSets (optional):

You can also remediate using Lambda or CloudFormation Stacksets:

  • Create Lambda functions to automatically update bucket policies or disable public access settings for flagged buckets
  • Use CloudFormation StackSets to deploy standardized bucket policies and S3 Block Public Access settings across multiple accounts

Verify your remediation

This section explains how to confirm that your fixes are effective before moving to ongoing monitoring. After applying remediation, verify the fix is effective before setting up ongoing monitoring:

  1. Re-run the audit Lambda function – Confirm the previously flagged buckets no longer appear in the risky buckets list.
  2. Check Security Hub compliance – Verify the compliance status has changed from FAILED to PASSED for Amazon S3-related controls.
  3. Validate with IAM Access Analyzer – Review findings for the remediated S3 buckets. Active findings should resolve automatically after public access is removed.
  4. Test application functionality – Confirm that legitimate workloads continue to function correctly.

Document the verification results for your auditing needs. If any S3 buckets still show issues, investigate whether the policy was applied correctly or if there are conflicting permissions.

Automation opportunities

This section covers optional strategies to automate ongoing detection and maintain your security posture without manual intervention.

  1. (Optional) Schedule recurring scans with Amazon EventBridge
    • Regular security scans help identify new issues arising from configuration changes or newly created S3 buckets. When new security risks are detected, Amazon SNS sends an alert and automatically initiates the remediation phase (Workflow 2 in Figure 1). To avoid repeated alerts, you can configure the audit Lambda function to run on a schedule and compare current results with the previous baseline to generate notifications when new findings are discovered.
    • For ongoing monitoring, you can schedule the audit Lambda function to run on a recurring basis using EventBridge. Create a scheduled rule with a cron expression (for example, daily at 6:00 AM UTC or weekly on Mondays), add the Lambda function as the target, and grant EventBridge permission to invoke it. See Amazon EventBridge scheduling documentation for instructions on creating scheduled rules and configuring targets.
  2. Enable IAM Access Analyzer for Amazon S3
    • IAM Access Analyzer monitors bucket policies, ACLs, and access points to identify buckets accessible from outside your account or organization. Create an analyzer scoped to your organization or individual account, then review findings to identify unintended external access. Findings automatically flow into Security Hub when both services are enabled, giving you a dashboard view for Amazon S3 security findings. See the IAM Access Analyzer documentation for setup and usage instructions.
  3. Automate notifications for policy drift
    • Recurring scans might surface new findings from policy drift or newly created buckets. When new risks are detected, Amazon SNS alert triggers and the remediation cycle repeat (as shown in Workflow 2 in Figure 1) sends email notifications. Configure the audit Lambda function to compare current scan results against the previous baseline and alert on new findings for ongoing reviews.

Clean up

This section lists the resources created during this walkthrough that you should review and remove when they are no longer needed. If the following services were not previously active in your account, leaving them enabled might result in additional ongoing charges. See the Cost considerations section for details. Review and remove unused resources to optimize costs.

Delete or disable the following script-generated resources if they’re not required after outputs are generated. Focus first on Lambda functions and EventBridge rules if you’re not running recurring scans. If you enabled AWS Config or Security Hub specifically for this audit, evaluate whether you need them for other compliance requirements before disabling.

  • Lambda – Functions, IAM roles, and policies created for auditing
  • Amazon EventBridge – Scheduled rules created for recurring audit triggers
  • Amazon SNS – Topics and subscriptions created for notifications
  • Amazon S3 – Buckets containing script-generated audit output files
  • AWS Config – Rules and recorders if no longer needed for compliance
  • Security Hub – Disable if enabled solely for this audit
  • IAM Access Analyzer – Delete the analyzer if no longer needed for ongoing monitoring

Note: Be careful when deleting data and consider temporarily disabling services first to check for dependencies. Only delete resources generated as part of your audit outputs. Verify you have retained any necessary results before proceeding. Verify resources are not used by other workloads before deletion.

Best practices

This section provides recommendations to maintain secure Amazon S3 configurations long-term. To learn more about maintaining secure Amazon S3 configurations, review the AWS documentation links provided in the conclusion. The following recommendations aren’t exhaustive. Adapt and extend them based on your organization’s evolving security requirements and AWS best practices guidance. After you’ve fixed existing issues, these practices help you maintain secure Amazon S3 configurations.

  • Start with account-level controls – Enable S3 Block Public Access at the account level. This prevents buckets from becoming public even if someone misconfigures an individual bucket policy. For multi-account environments, enforce this through AWS Organizations SCPs.
  • Automate detection – Use IAM Access Analyzer to detect external access. Schedule your audit Lambda function with EventBridge to catch new issues weekly or daily, depending on your change frequency. Compare scan results against previous baselines to identify drift.
  • Standardize across accounts – Use CloudFormation StackSets to deploy the same secure configuration to all accounts in your organization, reducing the chance of configuration drift. Use StackSets for IAM roles, AWS Config rules, and S3 Block Public Access settings.

Additional security measures

  • Regularly review and rotate cross-account IAM role credentials and external IDs
  • Implement Amazon S3 server-side encryption (SSE-S3 or SSE-KMS) for data at rest
  • Enable S3 access logging and AWS CloudTrail data events for audit trails

Conclusion

This section summarizes what you accomplished and suggests next steps to maintain your S3 security posture. By implementing the detection, remediation, and monitoring workflow outlined in this post, you can proactively identify and secure over-permissioned S3 buckets across your AWS environment. To maintain your ongoing security posture, enable IAM Access Analyzer for continuous monitoring and schedule recurring audits with EventBridge. To learn more about Amazon S3 security best practices, see Security best practices for Amazon S3

For more information:

If you have feedback about this post, submit comments in the Comments section below.
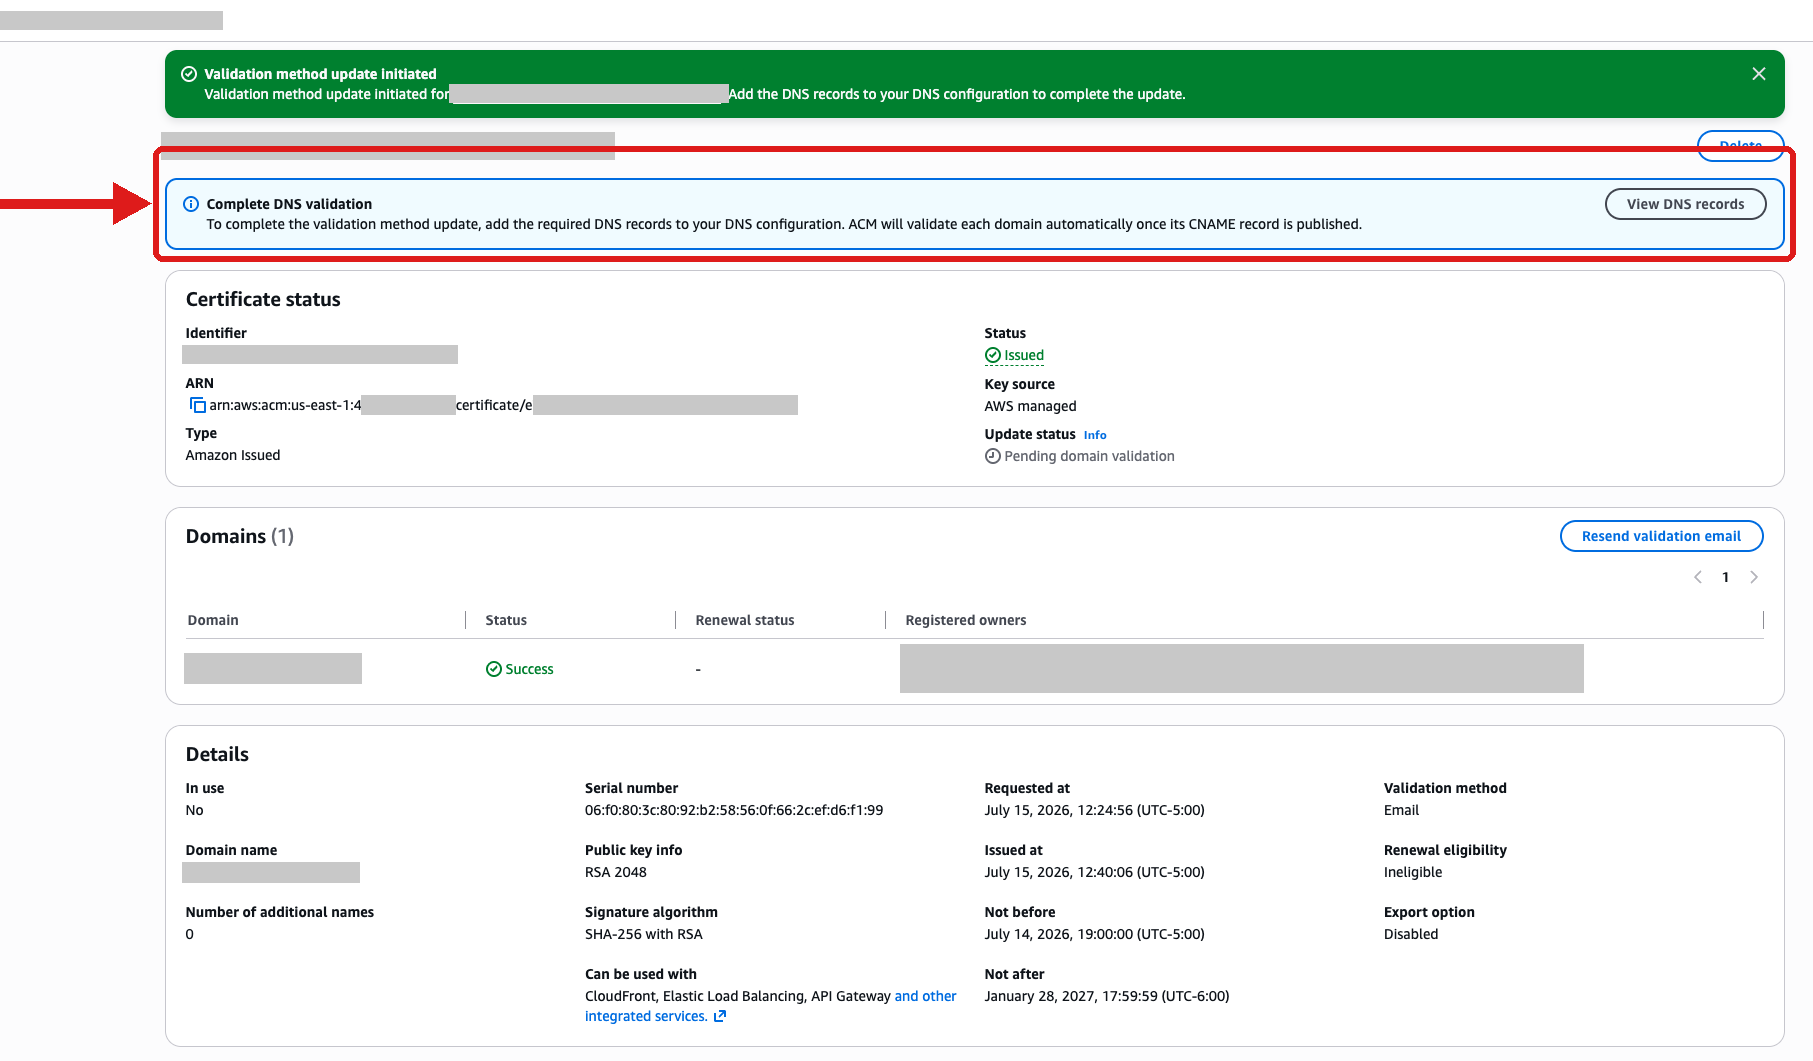

Hetal Kolekar

Hetal Kolekar

Hetal is a Sr. Technical Account Manager at AWS with more than 21 years of experience in Infrastructure Architecture, Security, Systems Engineering, and Consulting. He excels in leading teams to strengthen their cloud security posture and helps customers scale up their security using AWS services. Hetal is a guitarist and loves playing at church.

Manomayi Vedam

Manonmayi Vedam

Manonmayi is a Senior TAM and Product Owner at AWS, specializing in AI-driven cloud enablement, security, and generative AI risk across Healthcare, Financial Services, Energy, and Public Sector. She co-leads global security programs for Fortune 500 clients, contributes to the NIST Cyber AI Profile RMF and NCCoE, and is a Fellow at SCRS with recognition from GlobeeAwards and IEEE.

Fernando Freitas

Fernando Freitas

Fernando is a Sr. Technical Account Manager at AWS in Salt Lake City, focused on helping customers achieve their desired outcomes with the AWS Cloud. Fernando is passionate about Identity and Security, Training and Education.

Automate certificates with ACME support in AWS Certificate Manager

Post Syndicated from Anthony Harvey original https://aws.amazon.com/blogs/security/automate-certificates-with-acme-support-in-aws-certificate-manager/

Customers tell us that managing TLS certificates at scale is one of their biggest operational concerns. The Certification Authority Browser Forum (CA/Browser Forum) has mandated a phased reduction in maximum certificate validity for public certificates. By March 2027, the maximum validity drops to 100 days. By March 2029, it lasts for 47 days. For an organization managing 1,000 certificates, the final transition means roughly 30 renewal events every day. Renewal and rotations of renewed certificates at that cadence isn’t something manual processes or ticket-driven workflows can sustain at scale.

We recently announced Automated Certificate Management Environment (ACME) protocol support in AWS Certificate Manager (ACM). With this launch, you can use the ACME clients your teams already know, including popular open source tools like certbot, cert-manager, acme.sh, and win-acme, to automate public certificate issuance and renewal for your infrastructure. Customers that are using third-party certificate authorities (CAs) can point their existing ACME-compatible clients at ACM instead of their current CA, with minimal reconfiguration. This applies whether it’s running on Amazon Web Services (AWS), on premises, or in a hybrid environment. Certificates created through ACME are registered in ACM, giving you a unified view of your entire certificate inventory.

This post covers how the feature works, how to get started, and the controls and best practices to help you manage certificate issuance at scale.

Background

ACME is an open source protocol that automates the process of verifying domain ownership and issuing certificates and has become a standard mechanism for certificate automation. While ACM has long provided managed certificate issuance and renewal for AWS-integrated services such as Elastic Load Balancing (ELB), Amazon CloudFront, and Amazon API Gateway, many customers also need to automate certificates for their own infrastructure, including servers they manage in their data centers, Kubernetes clusters, Internet of Things (IoT) fleets, and hybrid environments. Until now, those customers had to turn to external providers. This launch brings the ACM automation model to that same infrastructure, using the standard ACME protocol with AWS managed certificate endpoints.

How it works

The feature introduces a new centrally provisioned and managed resource type: the ACME endpoint. Each endpoint is an AWS resource with a unique ACME directory URL and AWS Identity and Access Management (IAM)-based access controls. You create and manage endpoints through the ACM API or AWS Management Console, and point your existing ACME clients at the endpoint URL. Certificates issued through your endpoint are automatically registered with ACM, appearing in your certificate inventory alongside certificates created by the RequestCertificate and ImportCertificate API calls.

The architecture separates into two planes. In the control plane, PKI administrators use ACM APIs to create ACME endpoints, pre-approve the domains an endpoint is allowed to issue for, and generate external account binding (EAB) credentials. In the data plane, ACME clients register with an endpoint using EAB credentials and request certificates for domains the administrator has already validated. This architecture is how we provide customers the ability to scale. Instead of each client proving domain ownership on every request, a principal with appropriate ACM permissions (typically your PKI administrator) validates domains once at the endpoint level, and then application owners don’t need DNS credentials to get a certificate.

Adding to the data plane, EABs control client access to the endpoints. Each EAB is bound to an IAM role that controls what certificate operations the ACME client can perform, and credentials you generate in ACM are distributed to authorized ACME clients. An ACME client authorized for one endpoint can’t use a different endpoint. This creates security boundaries between environments. For example, a client authorized for your development endpoint can’t obtain certificates from your production endpoint.

Figure 1 shows the ACME request flow through ACM. An ACME client authenticates to an ACME endpoint using EAB credentials. The endpoint routes certificate orders to Amazon Trust Services for issuance. Issued certificates are registered in ACM inventory, where Amazon EventBridge and AWS CloudTrail provide expiration alerting and audit logging.

Figure 1: An ACME architecture and workflow

Figure 1: An ACME architecture and workflow

Getting started

Getting started with the new ACME feature in ACM is straightforward. Use the following steps to create your first ACME-generated certificate.

Prerequisites

  • An AWS account with permissions to create and manage ACM resources
  • An ACME client installed on your infrastructure (for example, Certbot, cert-manager, acme.sh, or others)
  • AWS Command Line Interface (AWS CLI) installed on your device (see this blog post for the console equivalent)
  • Amazon Route 53 hosted zone for your domain, or the ability to create a CNAME record with your DNS provider

Step 1: Create an ACME endpoint

Before you can use ACME clients with ACM, you need to create an ACME endpoint. This endpoint provides the URL that your ACME clients will use to request certificates.

  1. Run the following command from the AWS CLI to create an ACME endpoint:
    aws acm create-acme-endpoint \
      --authorization-behavior PRE_APPROVED \
      --certificate-authority '{"PublicCertificateAuthority":{"AllowedKeyAlgorithms":["EC_prime256v1"]}}

  2. Note the endpoint Amazon Resource Name (ARN) from the response.
    {"AcmeEndpointArn": "arn:aws:acm:us-east-1:123456789012:acme-endpoint/11111111-2222-3333-4444-555555555555"}

  3. Run the following command to retrieve the endpoint URL, replacing the ARN with your endpoint ARN:
    aws acm describe-acme-endpoint \
    --acme-endpoint-arn arn:aws:acm:us-east-1:123456789012:acme-endpoint/11111111-2222-3333-4444-555555555555

  4. Save the output of the ACME EndpointUrl:
    {
        "AcmeEndpoint": {
            "AcmeEndpointArn": "arn:aws:acm:us-east-1:123456789012:acme-endpoint/11111111-2222-3333-4444-555555555555",
            "EndpointUrl": "https://acm-acme-enroll.<region>.api.aws/6666666-7777-8888-9999-000000000000/directory",
            "Status": "ACTIVE",
            "AuthorizationBehavior": "PRE_APPROVED",
            "Contact": "REQUIRED",
            "CertificateAuthority": {
                "PublicCertificateAuthority": {
                    "AllowedKeyAlgorithms": [
                        "EC_prime256v1"
                    ]
                }
            },
            "CreatedAt": "2026-07-14T18:23:58.876000-04:00",
            "UpdatedAt": "2026-07-14T18:23:58.876000-04:00"
        }
    }
    

Step 2: Pre-approve a domain

Before ACME clients can request a certificate, the administrator validates the domain using DNS once at the endpoint level. Use DomainScope to control exactly which certificate patterns are allowed:

  • Enabling only ExactDomain restricts clients to that specific name,
  • Subdomains enabled allows names like api.example.com,
  • Wildcards enabled allows *.example.com.

Leave a scope disabled to block that pattern outright, even if an otherwise-valid ACME request asks for it. For a production endpoint, consider enabling only ExactDomain and Subdomains and leaving Wildcards disabled for a stricter posture.

aws acm create-acme-domain-validation \
--acme-endpoint-arn arn:aws:acm:us-east-1:123456789012:acme-endpoint/11111111-2222-3333-4444-555555555555 \
--domain-name example.com \
--prevalidation-options '{"DnsPrevalidation":{"DomainScope":{"ExactDomain":"ENABLED","Subdomains":"ENABLED","Wildcards":"DISABLED"},"HostedZoneId":"Z1234567890ABC"}}'

If your domain is hosted in Route 53, specifying HostedZoneId lets ACM create the required CNAME record automatically. If your domain is hosted elsewhere, omit it and create the provided CNAME record manually with your DNS provider. Validation typically completes within a few seconds after the record is in place.

You will receive the following response back:

{
    "AcmeDomainValidationArn": "arn:aws:acm:us-east-1:123456789012:acme-endpoint/1111111-2222-3333-4444-555555555555/acme-domain-validation/6666666-8888-9999-0000-11111111111"
}

Step 3: Generate EAB credentials

EAB credentials authenticate your ACME clients to your endpoint. Generate a unique set of credentials for each client or environment to maintain security boundaries.

  1. Run the following command to generate your EAB credentials, adjusting your expiration to fit your organization’s risk profile:
    aws acm create-acme-external-account-binding \
        --acme-endpoint-arn arn:aws:acm:region:111122223333:acme-endpoint/00000000-0000-0000-0000-000000000000 \
        --role-arn arn:aws:iam::111122223333:role/AcmeIssuanceRole \
        --expiration '{"Value": 7, "Type": "DAYS"}'

  2. Note the response from a successful invocation of the command
    {
        "ExternalAccountBinding": {
            "AcmeExternalAccountBindingArn": "arn:aws:acm:region:111122223333:acme-endpoint/00000000-0000-0000-0000-000000000000/acme-external-account-binding/1234567-1234-1234-1234-123456789012",
            "AcmeEndpointArn": "arn:aws:acm:region:111122223333:acme-endpoint/00000000-0000-0000-0000-000000000000",
            "RoleArn": "arn:aws:iam::123456789012:role/service-role/AcmAcmeIssuanceRole-XXXXXXXX",
            "ExpiresAt": "2026-07-21T18:47:50.641000-04:00"
        }
    }
    

  3. Run the following command to retrieve the credentials. You’ll need these values for your ACME client configuration the next step.
    aws acm get-acme-external-account-binding-credentials \
        --acme-external-account-binding-arn arn:aws:acm:region:111122223333:acme-endpoint/00000000-0000-0000-0000-000000000000/acme-external-account-binding/22222222-2222-2222-2222-222222222222

  4. Save the KeyId and MacKey for the next step.
    {
        "KeyId": "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx",
        "MacKey": "xxxxxxxx-xxxxxxxxxx-xxxxxxxxxxxxxxx"
    }

Step 4: Configure your ACME client

With your endpoint URL and EAB credentials ready, you can now configure your preferred ACME client. The following examples show configuration for two popular clients. As a reminder, the server information was retrieved in step 1, part 4 as the EndpointUrl.

acme.sh:

acme.sh --issue --server https://acm-acme-enroll.us-east-1.api.aws/123457-1234-1234-123456789012/directory \
    --eab-kid <KeyId> --eab-hmac-key <MacKey> \
    --email <EMAIL> \
    -d <DOMAIN> \
    --dns --yes-I-know-dns-manual-mode-enough-go-ahead-please

Certbot:

certbot certonly --standalone --non-interactive --agree-tos \
  --email <EMAIL> \
  --server https://acm-acme-enroll.us-east-1.api.aws/1234567-1234-1234-123456789012/directory \
  --eab-kid <KeyId> \
  --eab-hmac-key <MacKey> \
  -d <DOMAIN>

After the initial registration, your ACME client handles renewals.

Enterprise controls

Other ACME alternatives can provide certificates but don’t give the same amount of control and governance for customers that need to scale their certificate environment. The following controls are available to help reduce risk across your organization.

Domain validation

Customers managing large numbers of domains told us they need a way to prevent unauthorized certificate issuance across their domain space. Domain validation gives you this control. For each domain you validate, you enable the certificate patterns it should be allowed to issue, whether it’s ExactDomain, Subdomains, or Wildcards. For example, if you validate internal.example.com and enable only Wildcards, an ACME client can request *.internal.example.com but a request for internal.example.com itself or api.internal.example.com is rejected. This enforcement happens at the endpoint level, before requests reach the ACM certificate authority, and you can validate multiple domains under a single endpoint, each with its own scope.

Centralized certificate visibility

Certificates issued through your ACME endpoints are registered with ACM. You can use the aws acm list-certificates command to see all your issued certificates.

IAM authorization, CloudTrail audit logging and observability

Endpoint management operations are authorized through IAM and logged to CloudTrail. You can use IAM policies to control which principals can create endpoints, generate EAB credentials, and manage domain constraints.

Best practices

For customers implementing ACME certificates for the first time, consider the following best practices for your organizations.

Segment endpoints along organizational or environment boundaries

The endpoint serves as a useful method of isolation for larger organizations. A large enterprise can create one endpoint per organizational boundary (business unit, subsidiary, or environment) instead of a single shared endpoint company-wide. Each endpoint has its own pre-approved domains and its own set of EABs, so a compromised credential in one business unit has no path to certificates in another.

However, weigh this against your operational overhead as well. A reasonable starting point is one endpoint per environment (dev, staging, andprod) within a business unit, expanding to per-business-unit endpoints only where compliance or organizational requirements call for it.

Manage EAB credentials securely

Anyone holding a validKeyIdandMacKeyfor an endpoint can obtain certificates for any domain pre-approved on that endpoint, so these credentials deserve the same handling you’d give an access key.

  • Avoid hard coding theMacKeywhere possible by using a secret store such as AWS Secrets Manager. Distribute it only to the ACME clients that you authorize to use the endpoint.
  • Set the expiration of the EAB to an acceptable level. While EAB supports long-lived credentials, not all scenarios require an indefinitely long EAB.
  • When creating the role for each EAB, adhere to concept of least privilege. Creating a role per EAB, rather than sharing a role across all bindings, can help reduce risk in your AWS environment.
  • Audit CreateAcmeExternalAccountBinding and GetAcmeExternalAccountBindingCredentials calls in CloudTrail separately. Because retrieving the actual key material is a distinct API call from creating the binding, alerting on retrieval events is a stronger signal of real credential distribution than binding creation alone.

Automate how EABs are associated with clients at runtime

Generate a unique set of EAB credentials for each client or environment rather than sharing one binding across multiple ACME clients. As you begin to scale with multiple endpoints, usesome of the following patterns to reduce operational toil.

  • Name each EAB and its bound IAM role after the client it belongs to (team, application, environment), so the binding’s purpose is obvious from DescribeAcmeExternalAccountBinding output alone, without cross-referencing a spreadsheet.
  • Store each client’s KeyId and MacKey under a secrets path scoped to that client (for example, a Secrets Manager path per team and environment), and let the client’s provisioning pipeline retrieve its own credentials.
  • In Kubernetes, use one ClusterIssuer or namespace-scoped Issuer per EAB rather than one shared issuer across teams. This keeps the client-to-EAB association explicit in cluster config, and lets you revoke one team’s access without touching anyone else’s.
  • For ephemeral infrastructure (build agents, autoscaled fleets), provision EAB credentials as part of your infrastructure-as-code or continuous integration and deployment (CI/CD) pipeline instead of a one-time manual handoff, so credential lifecycle tracks infrastructure lifecycle.

Monitor your deployment of ACME

ACME’s power is through automation, and organizations should monitor their ACME usage for anomalies.

  • Alarm on issuance failures, not just successes. At 45-day certificate validity, a silent renewal failure gives you far less runway to react than the months of time you might be used to with longer-lived certificates.
  • Test renewal automation before you depend on it. Force a manual renewal against a non-production endpoint and confirm your client, monitoring, and on-call runbooks behave as expected, before the CA/Browser Forum’s shortened validity windows turn a failed renewal into a disruptive event for your organization.

Availability and pricing

ACME support in AWS Certificate Manager is available today in all commercial AWS Regions and will be available in AWS GovCloud (US), the China Regions, and the AWS European Sovereign Cloud partitions at a later date. See the ACM pricing page for more information on ACME pricing.

Conclusion

The phased reduction in certificate validity can’t easily be solved without automation. ACME support in ACM gives you that automation through a standard protocol and standard tooling, while keeping the visibility and governance controls your security teams rely on from ACM.

To get started, see the AWS Certificate Manager documentation or follow the getting started guide.

If you have feedback about this post, submit comments in the Comments section below.
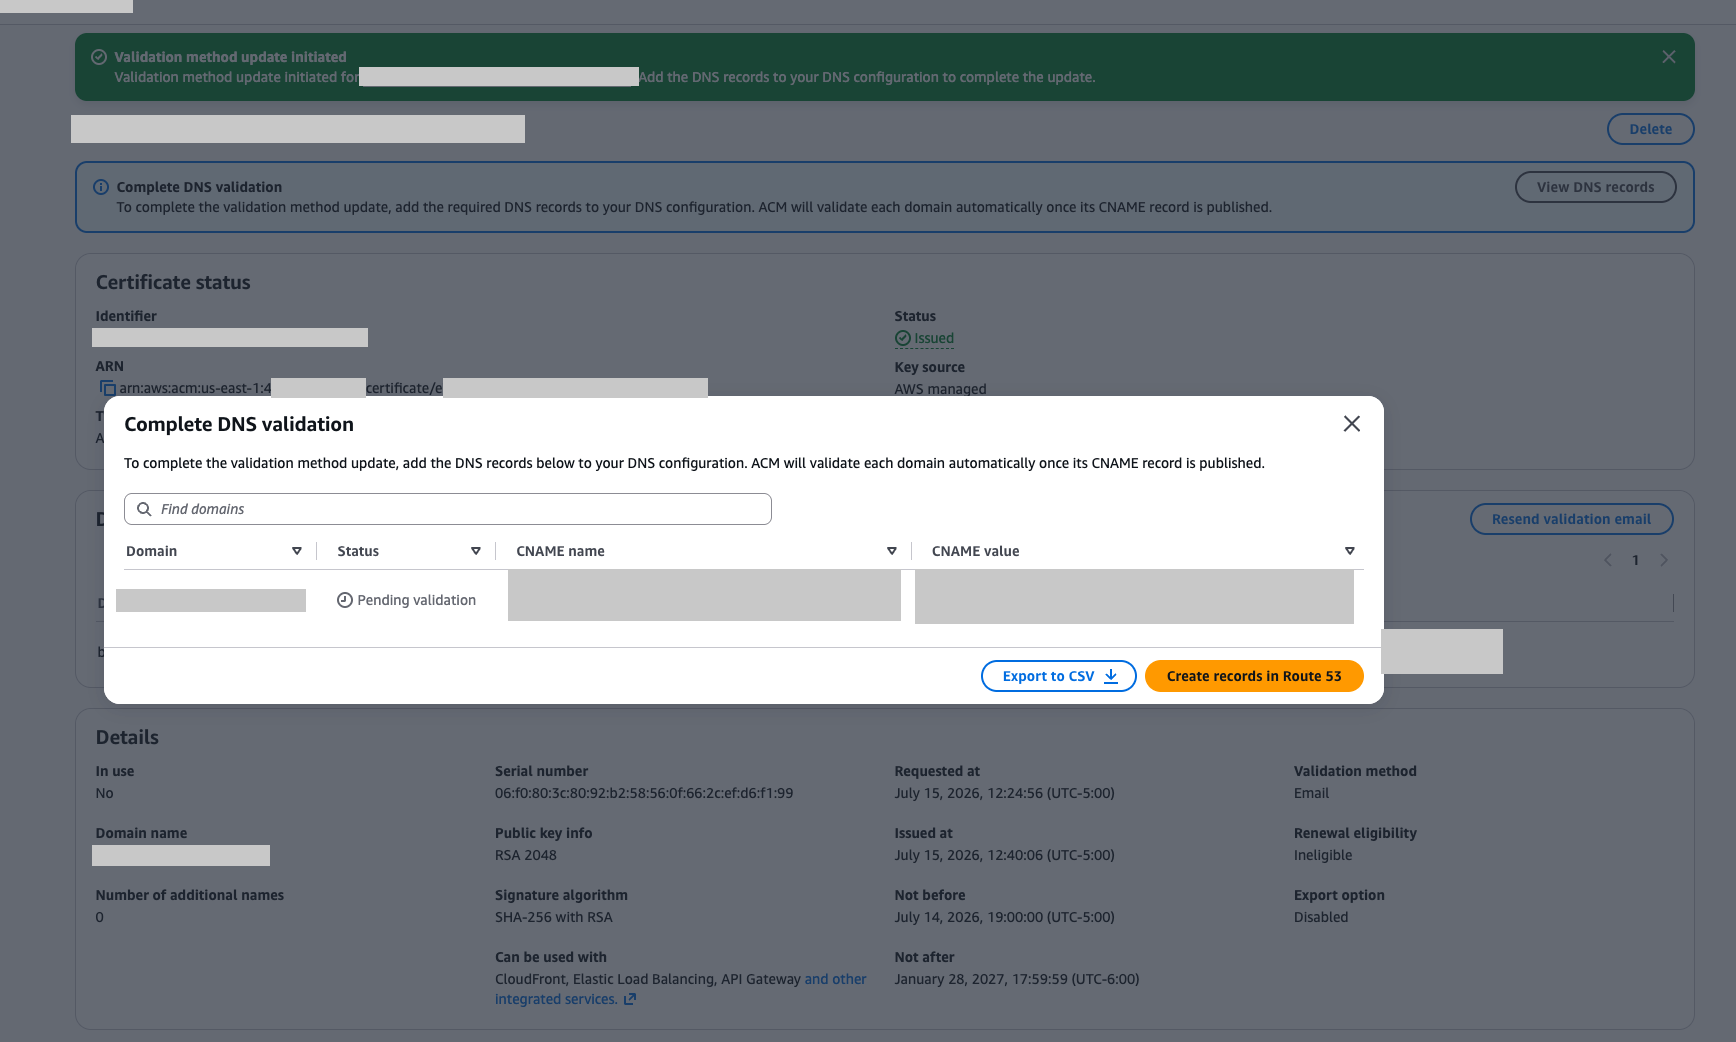

Anthony Harvey

Anthony Harvey

Anthony is a Senior Security Specialist Solutions Architect for AWS in the worldwide public sector group. Prior to joining AWS, he was a chief information security officer in local government for half a decade. With his public sector experience, he has a passion for figuring out how to do more with less and leveraging that mindset to enable customers in their security journey.

Chandan Kundapur

Chandan Kundapur

Chandan is a Principal Product Manager on the AWS Certificate Manager (ACM) team. With over 15 years of cybersecurity experience, he has a passion for driving PKI product strategy.

Route Amazon Bedrock Guardrails interventions to Amazon Security Lake

Post Syndicated from Dhananjay Karanjkar original https://aws.amazon.com/blogs/security/route-amazon-bedrock-guardrails-interventions-to-amazon-security-lake/

Security teams investigating AI-related incidents need guardrail intervention data alongside their existing security telemetry. Routing Amazon Bedrock Guardrails violations to Amazon Security Lake makes this possible. With this integration, you can query guardrail events alongside identity, network, and application security data in a single layer. When a guardrail blocks a prompt injection attempt or redacts sensitive data, that intervention carries investigative value comparable to a failed sign-in or a network intrusion alert. Amazon Bedrock publishes this telemetry to Amazon CloudWatch metrics and model invocation logs for operational monitoring. By using Security Lake, organizations can extend this telemetry into their security data lake for unified correlation.

In this post, I show you how to build an automated pipeline that transforms Amazon Bedrock Guardrails intervention events into Open Cybersecurity Schema Framework (OCSF) records and delivers them to Security Lake as a custom source. You can query the data using Amazon Athena or any Security Lake subscriber.

Use case

Consider a financial services organization deploying Amazon Bedrock across multiple business units. Each unit uses guardrails to enforce content policies (blocking harmful content), topic policies (preventing off-topic queries about competitors), sensitive information policies (redacting personally identifiable information (PII) such as account numbers), and prompt injection detection.

The security team needs to:

  • Identify which user accounts trigger the most guardrail interventions and whether those accounts also have unusual AWS Identity and Access Management (IAM) activity
  • Determine if prompt injection attempts correlate with specific source IP addresses that also appear in Amazon Virtual Private Cloud (Amazon VPC) Flow Logs
  • Track the organization-wide trend of guardrail violations across all business units and compare it against the baseline from 30 days ago

With guardrail events routed to Security Lake, a single Athena query covers all three.

Solution overview

The pipeline architecture routes Amazon Bedrock security events to Security Lake as OCSF-compliant records. The same infrastructure—subscription filter, AWS Lambda transformation, Parquet writer, Amazon Simple Storage Service (Amazon S3) partitioning—supports multiple event types by changing the filter pattern and OCSF mapping:

Guardrail interventions (this post) DETECTION_FINDING 2004
Model invocation API calls API_ACTIVITY 6003
Agent guardrail traces DETECTION_FINDING 2004
Token consumption anomalies DETECTION_FINDING 2004

This post demonstrates the guardrail interventions implementation as a working example. The solution captures Amazon Bedrock model invocation logs that contain guardrail trace data and filters for intervention events. It transforms matching events into OCSF-compliant Detection Finding records (class_uid 2004) and delivers them to Security Lake as Parquet files. Guardrail interventions are detection events: the guardrail detected and blocked prohibited content, so OCSF class 2004 (Detection Finding) under the Findings category is the appropriate classification.

Architecture

The following diagram shows the end-to-end pipeline from guardrail intervention to Security Lake ingestion.

Figure 1: Guardrail intervention routing

Figure 1: Guardrail intervention routing

The data flow consists of the following steps:

  1. An application calls Amazon Bedrock (InvokeModel or Converse API) with a guardrail attached.
  2. Amazon Bedrock evaluates the guardrail and logs the invocation (including guardrail trace data) to a CloudWatch Logs log group using model invocation logging. The subscription filter matches log entries where the guardrail action is INTERVENED (blocked or masked content).
  3. The subscription filter delivers matching records to a Lambda function (OCSF Transform).
  4. The Lambda function transforms each intervention event into an OCSF Detection Finding record (class_uid 2004), batches records, and converts them to Zstandard (zstd)-compressed Apache Parquet format. It writes the Parquet file to the Amazon S3 Security Lake bucket using the required partition path (ext/BedrockGuardrails/region=/accountId=/eventDay=/). If the Lambda function fails to process a record, the message routes to an Amazon Simple Queue Service (Amazon SQS) dead-letter queue for later analysis and redrive.
  5. Security Lake manages the ingested Parquet data in the S3 bucket.
  6. AWS Glue crawler detects new partitions and catalogs the Parquet files for query access.
  7. SOC analysts query guardrail violation data alongside other security sources using Athena.

OCSF mapping

The following table shows how Amazon Bedrock Guardrails intervention fields map to OCSF Detection Finding (class_uid 2004) attributes.

OCSF field Source Example value
class_uid Static 2004 (Detection Finding)
category_uid Static 2 (Findings)
severity_id Derived from policy type 3 (Medium) for content/topic; 4 (High) for prompt injection
activity_id Static 1 (Create)
time Invocation log timestamp 1721001600000
cloud.provider Static AWS
cloud.region Invocation log region us-east-1
cloud.account.uid Invocation log accountId 123456789012
actor.user.uid Invocation log identity.arn arn:aws:sts::123456789012:assumed-role/AppRole/session
finding_info.title Derived from policy type ContentPolicy Intervention
finding_info.desc Guardrail trace action/topic Blocked: HATE content detected on INPUT
resource.uid Model ARN arn:aws:bedrock:us-east-1::foundation-model/anthropic.claude-sonnet-4-6-20250514-v1:0
resource.type Static AwsBedrock:Model
metadata.product.name Static Amazon Bedrock Guardrails
metadata.product.vendor_name Static AWS
metadata.version Static 1.3.0
unmapped.guardrail_id Guardrail trace guardrailId my-content-guardrail
unmapped.guardrail_arn Guardrail trace guardrailArn arn:aws:bedrock:us-east-1:123456789012:guardrail/abc123
unmapped.guardrail_version Guardrail trace guardrailVersion 3
unmapped.guardrail_content_source Guardrail trace INPUT or OUTPUT
unmapped.guardrail_policy_type Guardrail trace ContentPolicy, TopicPolicy, SensitiveInformationPolicy, WordPolicy, ContextualGroundingPolicy, PromptAttack

Prerequisites

The following prerequisites are needed to deploy the reference implementation. Before you begin, clone the repository:

git clone https://github.com/aws-samples/sample-bedrock-guardrails-security-lake.git
cd sample-bedrock-guardrails-security-lake

Verify you have the following:

  • An AWS account with AWS Cloud Development Kit (AWS CDK) bootstrapped in the target AWS Region
  • Security Lake enabled in the target Region
  • Python 3.12 or later
  • Node.js 20 or later (for AWS CDK CLI)
  • An existing Amazon Bedrock guardrail (or create one during deployment)
  • Model invocation logging enabled on Amazon Bedrock (with guardrail trace data enabled)

Implementation

The reference implementation deploys three CloudFormation stacks: SecurityLakeSourceStack, TransformPipelineStack and MonitoringStack. The following commands deploy the stacks in dependency order:

cdk deploy SecurityLakeSourceStack \
  -c security_lake_bucket=<your-security-lake-bucket> \
  -c source_location=ext/BedrockGuardrails \
  -c security_lake_enabled=true

cdk deploy TransformPipelineStack \
  -c security_lake_bucket=<your-security-lake-bucket> \
  -c source_location=ext/BedrockGuardrails

cdk deploy MonitoringStack \
  -c security_lake_bucket=<your-security-lake-bucket> \
  -c source_location=ext/BedrockGuardrails

Enable model invocation logging

Model invocation logging captures the guardrail trace data you need. Turn on full request and response logging to a CloudWatch Logs log group. Configure textDataDeliveryEnabled to capture text request and response bodies, which include the guardrail trace output when a guardrail is attached to the invocation.

Register Security Lake custom source

Register BedrockGuardrails as a custom source with Security Lake using the DETECTION_FINDING event class. Security Lake creates the Amazon S3 prefix and IAM role for your source. The stack configures the AWS Glue crawler role for partition discovery.

Create the subscription filter

Create a CloudWatch Logs subscription filter on your model invocation log group with the filter pattern { $.output.guardrailAction = “INTERVENED” }. This captures only the events where a guardrail blocked or modified content, not the successful pass-through events. This reduces Lambda invocations and cost.

Transform to OCSF and write Parquet

The Lambda function performs three operations: parse the CloudWatch Logs event, transform each intervention to an OCSF Detection Finding record (class_uid 2004), and write batched records as Parquet files. The files are written to the Security Lake S3 bucket using the required partition path (ext/BedrockGuardrails/region=<region>/accountId=<accountId>/eventDay=<YYYYMMDD>/).

The transformation maps guardrail trace fields to OCSF attributes as described in the OCSF mapping table. Severity is set to High for prompt injection interventions and Medium for content, topic, or sensitive information interventions. For a concrete before-and-after example, see the sample invocation log and corresponding OCSF output in the companion repository.

Scaling considerations: At low intervention volumes (tens of events per hour), direct Lambda writes produce acceptably sized Parquet files. For higher volumes, consider buffering through Amazon Data Firehose with its native Parquet conversion and 5-minute buffering interval to produce fewer, larger files that optimize Athena query performance.

Multi-account deployment: The partition scheme (accountId=<account>) already supports multi-account environments. Deploy the subscription filter and transform pipeline in each workload account where model invocation logging is enabled. Each pipeline writes cross-account to the delegated-administrator Security Lake bucket. Distribute the pipeline using CloudFormation StackSets across the organization.

Query violations in Athena

After deployment, guardrail violations typically appear in your Security Lake tables within 5–10 minutes, depending on the AWS Glue crawler schedule. You can then run cross-service correlation queries. The following example identifies users who trigger both prompt injection interventions and unusual IAM activity:

WITH guardrail_violators AS (
    SELECT actor.user.uid AS user_arn, COUNT(*) AS violation_count
    FROM "amazon_security_lake_glue_db_us_east_1"."amazon_security_lake_table_us_east_1_bedrockguardrails"
    WHERE eventDay >= '20260701'
      AND unmapped.guardrail_policy_type = 'PromptAttack'
    GROUP BY actor.user.uid
),
iam_failures AS (
    SELECT actor.user.uid AS user_arn, COUNT(*) AS failure_count
    FROM "amazon_security_lake_glue_db_us_east_1"."amazon_security_lake_table_us_east_1_cloud_trail_mgmt_2_0"
    WHERE eventDay >= '20260701'
      AND status_id = 2
    GROUP BY actor.user.uid
)
SELECT g.user_arn, g.violation_count, i.failure_count
FROM guardrail_violators g
JOIN iam_failures i ON g.user_arn = i.user_arn
ORDER BY g.violation_count DESC;

You can also track violation trends by policy type over time to establish baselines and detect spikes. The following query shows the 30-day trend:

SELECT eventDay,
       unmapped.guardrail_policy_type AS policy_type,
       COUNT(*) AS violation_count
FROM "amazon_security_lake_glue_db_us_east_1"."amazon_security_lake_table_us_east_1_bedrockguardrails"
WHERE eventDay >= '20260623'
GROUP BY eventDay, unmapped.guardrail_policy_type
ORDER BY eventDay, violation_count DESC;

The OCSF mapping has been validated against schema version 1.3.0, and the Security Lake AWS Glue crawler correctly detects the partitioned Parquet files for querying.

Alternative for teams not yet using Security Lake: If your organization hasn’t adopted Security Lake, you can query guardrail intervention events directly in CloudWatch Logs Insights using the same subscription filter log group. CloudWatch Logs Insights supports cross-log-group queries, so you can correlate guardrail events with other CloudWatch log sources without the OCSF transformation step. Security Lake adds value when you need to join with non-CloudWatch sources in a single query layer. Examples include Amazon VPC Flow Logs, Amazon Route 53 DNS logs, and third-party findings.

Clean up

To avoid ongoing charges, destroy the stacks in reverse dependency order:

cdk destroy MonitoringStack --force \
  -c security_lake_bucket=<your-security-lake-bucket> \
  -c source_location=ext/BedrockGuardrails

cdk destroy TransformPipelineStack --force \
  -c security_lake_bucket=<your-security-lake-bucket> \
  -c source_location=ext/BedrockGuardrails

cdk destroy SecurityLakeSourceStack --force \
  -c security_lake_bucket=<your-security-lake-bucket> \
  -c source_location=ext/BedrockGuardrails \
  -c security_lake_enabled=true

Conclusion

In this post, you learned how to route Amazon Bedrock Guardrails intervention events to Amazon Security Lake as OCSF-compliant Detection Finding records. This integration extends guardrail telemetry from Amazon CloudWatch into your security data lake. Security analysts can then run cross-service correlation of AI intervention events with IAM, network, and application telemetry.

The pipeline filters for intervention events only, keeping costs low while capturing the security-relevant signals. The records use OCSF event class 2004 (Detection Finding), which integrates with supported Security Lake subscribers such as Amazon OpenSearch Service and third-party SIEM tools.

Clone the reference implementation and adapt the OCSF mapping and subscription filter to your organization’s guardrail configuration.

References

If you have feedback about this post, submit comments in the Comments section below.
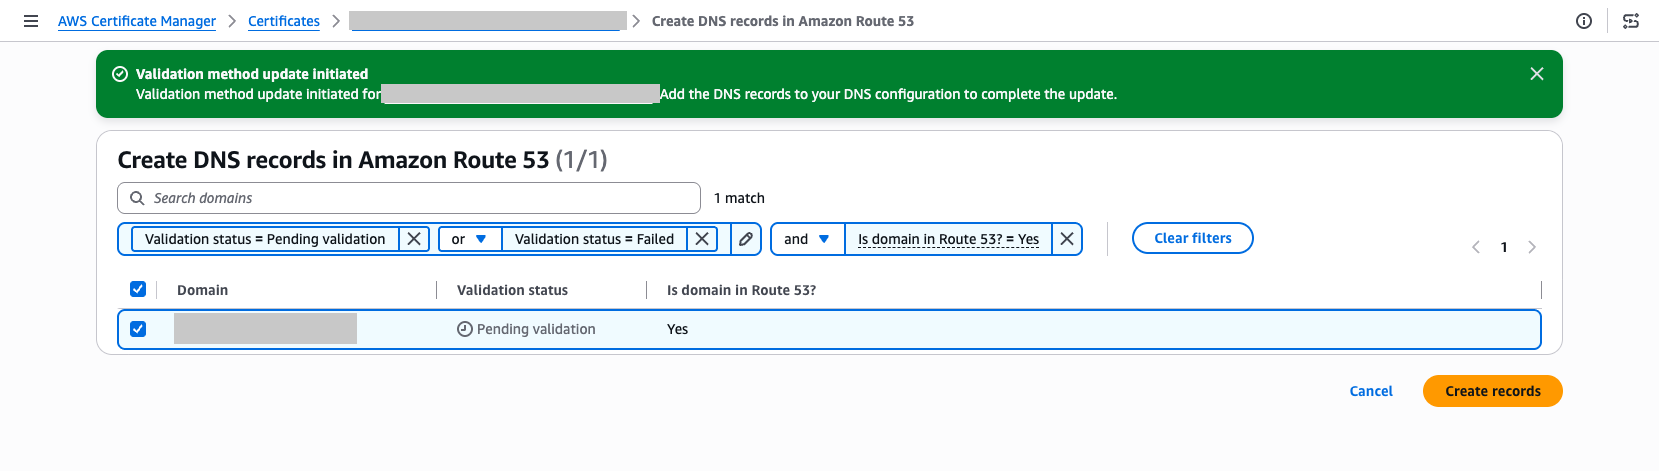

Dhananjay Karanjkar

Dhananjay Karanjkar

Dhananjay is a Senior Lead Consultant at AWS Professional Services, specializing in agentic AI systems, multi-agent orchestration, and generative AI security. He holds two US patents and serves as a Responsible AI Champion, with a background spanning financial services, enterprise consulting, and enterprise-scale AI delivery. When not architecting AI solutions, he trains for triathlons, paints oil portraits, and is an avid reader.

Caching KMS data keys in multi-thread environments: Per-tenant encryption for event-driven systems at scale

Post Syndicated from Maria Gutovsky original https://aws.amazon.com/blogs/security/caching-kms-data-keys-in-multi-thread-environments-per-tenant-encryption-for-event-driven-systems-at-scale/

This post assumes familiarity with envelope encryption and the AWS Encryption SDK.

When your encryption system generates millions of duplicate API calls per hour, costs spiral and performance degrades. That’s exactly the challenge NICE Actimize faced while operating their global-scale, event-driven financial crime detection platform on Amazon Web Services (AWS).

NICE Actimize, a leading provider of financial crime, risk, and compliance solutions, processes millions of encrypted messages daily across hundreds of tenants. By rethinking how they cache encryption keys, they reduced their AWS Key Management Service (AWS KMS) costs by 77% while maintaining strict security guarantees and per-tenant encryption isolation.

In this post, we explore the cache stampede problem that emerges when envelope encryption meets high-concurrency, multi-tenant architectures. We walk through two solutions: the AWS-recommended hierarchical keyring pattern and a custom caching approach that NICE Actimize built for their regulated environment. These patterns apply to multi-tenant software as a service (SaaS) environments and high-throughput systems where per-tenant encryption generates significant KMS API volume.

Why per-tenant encryption matters

Financial services systems operate under strict regulatory requirements. You must encrypt data at rest and in transit. For multi-tenant SaaS providers, this requirement might go further: each tenant’s data must be encrypted with separate keys to provide complete cryptographic isolation. If one tenant’s key is compromised, no other tenant’s data is at risk.

Consider an enterprise SaaS environment built on an event-driven architecture using Amazon Managed Streaming for Apache Kafka (Amazon MSK), with many different databases for storing data and Amazon Simple Queue Service (Amazon SQS) for messaging. Messages flow continuously between producers and consumers, and each message must be encrypted with the correct tenant-specific key. At scale with millions of messages daily across hundreds of tenants, this creates a massive volume of encryption and decryption operations.

To handle this volume efficiently, the standard approach is envelope encryption: a two-tier model where an AWS KMS key encrypts short-lived data keys, and those data keys encrypt the actual data. Your application can encrypt large volumes of data locally without calling AWS KMS for every operation, reducing latency and costs.

The cache stampede problem

Envelope encryption reduces AWS KMS calls, but it doesn’t eliminate them. Each encrypt operation still requires a data key, either generated fresh using GenerateDataKey or retrieved from a cache, and each decrypt operation must unwrap an encrypted data key (EDK) by calling Decrypt. In high-throughput systems processing millions of messages, these calls add up quickly.

The AWS Encryption SDK provides a built-in solution for this: the CachingCryptoMaterialsManager. This component caches data encryption materials (data keys) locally, so your application can reuse them across multiple operations without calling AWS KMS each time. You configure a time-to-live (TTL), a maximum message-use limit, and a local cache, and the SDK handles the rest.

This approach works well under moderate load when you partition the cache by tenant AWS KMS key Amazon Resource Name (ARN) so that each tenant’s encryption materials remain cryptographically isolated. However, a critical problem emerges as concurrency scales to hundreds of threads processing millions of encrypted messages in parallel: the cache stampede, also known as the thundering herd problem.

How the stampede occurs

The CachingCryptoMaterialsManager caches the result of the SDK’s internal getMaterialsForEncrypt and decryptMaterials calls at the materials level. The cache stampede, however, happens at the KMS API call level. When a cached data key expires or a new, previously-unseen EDK arrives, the following sequence unfolds:

  1. On encrypt – data key explosion: Multiple threads simultaneously call encrypt() for the same tenant. Each thread finds the cache entry expired and independently calls GenerateDataKey against AWS KMS. Instead of one thread generating a data key while others wait, N threads create N distinct data keys. Each new data key produces a unique EDK, which inflates the EDK cardinality across the system.
  2. On decrypt – redundant unwrap calls: Those extra unique EDKs propagate downstream. When consumers later read encrypted records, each distinct EDK is a separate cache key. Multiple threads encountering the same EDK simultaneously each trigger an independent Decrypt call to AWS KMS because the cache has no coordination mechanism to make competing threads wait for a single in-flight request.
  3. Compounding effect: The encrypt-side stampede creates excess EDK cardinality, which degrades the decrypt-side cache hit ratio, which triggers more KMS calls, which drives up costs further. In the NICE Actimize case, this produced a ratio of 30% unique data keys to data records in DynamoDB tables, meaning nearly one in three records was encrypted with a different data key.

At enterprise SaaS scale, this compounding effect can generate millions of redundant AWS KMS GenerateDataKey and Decrypt calls per hour, even with the SDK’s built-in caching enabled. The following figure shows the pattern leading to a stampede.

Figure 1: Cache stampede – multiple threads independently calling AWS KMS for the same encrypted data key, creating duplicate requests

Figure 1: Cache stampede – multiple threads independently calling AWS KMS for the same encrypted data key, creating duplicate requests

The stampede follows this sequence on the encrypt side:

  1. Multiple threads call encrypt() for the same tenant concurrently.
  2. Each thread checks the CachingCryptoMaterialsManager and finds the cache entry expired.
  3. With no coordination mechanism, each thread independently calls GenerateDataKey.
  4. AWS KMS returns N distinct data keys (one per thread).
  5. Each data key produces a unique EDK, inflating cardinality across the system.

On the decrypt side, the inflated EDK cardinality compounds the problem:

  1. Consumer threads encounter unique EDKs that were never cached.
  2. Multiple threads hitting the same EDK simultaneously each trigger a separate Decrypt call. AWS KMS returns the same plaintext data key N times, doing redundant work.

Two paths forward

We evaluated two approaches to solve the cache stampede problem. Each fits different architectural requirements and regulatory constraints.

Option A: Hierarchical keyring with DynamoDB (AWS-recommended)

AWS addresses the cache stampede challenge through the hierarchical keyring pattern, which introduces an additional level of key hierarchy that significantly reduces how often cache stampedes occur.

In this architecture, branch keys serve as intermediate wrapping keys stored in a DynamoDB table. This DynamoDB table acts as a shared cache layer that coordinates across all instances in your distributed fleet.

Figure 2: Hierarchical keyring architecture – branch keys in DynamoDB coordinating across distributed instances

Figure 2: Hierarchical keyring architecture – branch keys in DynamoDB coordinating across distributed instances

The architecture (shown in Figure 2) works as follows:

  1. The application requests encryption through the hierarchical keyring.
  2. The keyring checks the local cache for the tenant’s branch key.
  3. On a cache miss, it queries the DynamoDB Key Store table for the active branch key.
  4. AWS KMS decrypts the branch key (this is the only KMS call in the flow).
  5. The decrypted branch key is returned to the keyring.
  6. The keyring stores the branch key in the local cache for subsequent requests.
  7. The keyring derives a unique wrapping key from the branch key and generates the data key locally.

The key insight is that the cache is thread-aware. When the cache expires, threads coordinate to make a single request to refresh the cache. Only a single thread is used to make a call to the branch key, rather than all the threads acting independently. Additionally, by adding an additional key into the key hierarchy, branch keys don’t live within AWS KMS. This means cache misses and the stampedes they trigger interact with the branch key, and don’t make as many calls to the AWS KMS service at the top of the hierarchy:

  • Without hierarchical keyrings: Your local cache needs to store all the data encryption keys, and has constant misses as new, unique data keys arrive with each encrypted message. A miss can trigger a stampede.
  • With hierarchical keyrings: The same branch key wraps thousands or millions of data keys. A cache miss only occurs when a branch key expires or is first requested, which happens orders of magnitude less frequently than without hierarchical keyrings.

The DynamoDB table acts as a coordination point. The first thread to request a missing branch key retrieves it from AWS KMS and stores it in DynamoDB (the Key Store table). Subsequent requests from instances in the fleet retrieve the cached branch key from DynamoDB instead of making duplicate AWS KMS calls.

Beyond reducing cache miss frequency, the hierarchical keyring provides built-in stampede protection within its local cache implementation. The SDK offers multiple cache types, and the Default cache, designed for heavily multi-threaded environments, prevents multiple threads from calling AWS KMS on cache expiry by notifying a single thread that the branch key materials entry is about to expire 10 seconds in advance. That one thread refreshes the cache while all other threads continue serving requests using the still-valid entry.

This solution integrates with the AWS Encryption SDK and requires minimal code changes to existing applications. For event-driven architectures processing encrypted Kafka streams, this approach reduces KMS call volume by orders of magnitude while preserving per-tenant cryptographic isolation.

Option B: Custom KMS client caching – Solving the stampede at the API layer

While the hierarchical keyring (Option A) addresses the stampede by reducing how often cache misses occur, there’s a complementary approach: eliminating the stampede at its source by caching KMS API responses directly, using atomic, single-flight cache loading that prevents concurrent threads from issuing duplicate calls. This is the path NICE Actimize took.

The IClientSupplier extension point in AWS Encryption SDK v3

In the AWS Encryption SDK v2, decorating the AWS KMS client on a per-request basis was possible through the RegionalClientSupplier interface, but it was an advanced and undocumented use case. Without explicit guidance or a supported pattern, caching strategies typically operated above the SDK layer, making it difficult to prevent duplicate KMS calls at their source. The AWS Encryption SDK v3 introduced the IClientSupplier interface, which the AwsKmsMrkMultiKeyring accepts at construction time. This interface is called by the SDK whenever it needs a KMS client for a given AWS Region, and you control what it returns, making it possible to insert a caching layer between the SDK and AWS KMS.

Architecture: A decorated KMS client with two Caffeine caches
The solution is a CachedKmsClient—a decorator that wraps the standard AWS SDK KmsClient and interposes two Caffeine LoadingCache instances between the application and AWS KMS:

Cache Key Value Purpose
GenerateDataKey cache GenerateDataKeyRequest (tenant KMS key ARN and key spec) GenerateDataKeyResponse (EDK and plaintext data key) Ensures encrypt operations on the same node reuse the same data key for a given tenant KMS key during the cache window
Decrypt cache DecryptRequest (EDK and key ARN) DecryptResponse (plaintext data key) Ensures decrypt operations for the same EDK share a single KMS call result

Both caches are configured with refreshAfterWrite (default: 1 hour, configurable), which means:

  • During the refresh window, concurrent threads receive the cached response instantly resulting in zero KMS calls.
  • When a cache entry expires, Caffeine’s LoadingCache.get() guarantees that exactly one thread executes the loader function (the actual KMS API call), while all other concurrent threads block and wait for that single result. This is the atomic, single-flight property that eliminates the stampede.

Security consideration: Caching plaintext data keys in memory means the keys exist in process memory for the duration of the cache TTL. The TTL acts as a security control: shorter TTLs reduce the window of exposure in the event of a memory dump, while longer TTLs reduce KMS call volume. Choose a TTL that balances your security requirements with your cost and performance goals. Key rotation at the KMS key level remains unaffected by the cache, because rotated keys produce new data keys on the next cache refresh.

Integration with the AWS Encryption SDK v3

The integration is minimal. The IClientSupplier AWS Lambda function returns a CachedKmsClient singleton for each AWS Region, this singleton is passed into the AwsKmsMrkMultiKeyring at keyring construction time. From that point forward, each GenerateDataKey and Decrypt call the SDK makes flows through the caching decorator transparently, with no changes to the encrypt or decrypt call sites.

The CachedKmsClient is a singleton per Region (managed using a ConcurrentHashMap), so all tenants on the same node share the same caching layer but their data keys remain fully isolated because the cache keys include the tenant-specific AWS KMS key ARN.

Why Caffeine?

Caffeine is a high-performance, near-optimal Java caching library well-suited for this pattern for several reasons:

  • Atomic loading: LoadingCache.get() guarantees that on a cache miss, only one thread executes the loader while others wait. This is the core property that eliminates the stampede.
  • refreshAfterWrite semantics: Unlike expireAfterWrite (which blocks all threads during refresh), refreshAfterWrite allows one thread to asynchronously reload the entry while other threads continue to serve the stale-but-valid cached value. This eliminates latency spikes during key rotation.
  • Observability: Cache eviction listeners and Micrometer metric counters can be wired in to track actual KMS call volume per tenant KMS key, enabling real-time cost monitoring.

Choosing between the two options

The hierarchical keyring with DynamoDB (Option A) is a production-ready, AWS-recommended solution that reduces stampede frequency by introducing longer-lived branch keys. It’s the best choice for most organizations. Particularly when starting fresh or when the operational overhead of an additional data store is acceptable.

NICE Actimize chose the custom caching approach (Option B) for a pragmatic reason: it avoided introducing a new infrastructure dependency into the encryption critical path. Their platform already operated at scale across hundreds of tenants, and adding a DynamoDB table as a key coordination layer would have meant taking on additional operational responsibility: provisioning, monitoring, backup, access control, and ensuring high availability for a component that sits directly in the encrypt/decrypt hot path. In a regulated financial services environment, each new stateful component in the security chain requires its own resilience planning, failure-mode analysis, and compliance review. The Caffeine cache used in Option B, by contrast, is an in-process library (a JAR on the classpath). It is stateless, requires no network calls, no provisioning and no operational overhead. It makes a lighter dependency than a managed cloud resource in the critical path. There is no shared state to lose, no additional infrastructure to protect, and no new failure mode beyond what already exists with AWS KMS itself. If a node restarts, the cache rebuilds on the next KMS call.

Results

By implementing a rotation policy with the optimized caching approach, NICE Actimize achieved the following results:

  • 77% reduction in AWS KMS costs – Eliminating millions of redundant API calls translated directly into significant cost savings.
  • Maintained strict per-tenant isolation – Per-tenant encryption isolation remained fully intact, with no compromise to their security posture.
  • Improved system performance – Removing the stampede of duplicate AWS KMS calls reduced latency and freed up system resources for core processing.
  • Simplified operations – A coordinated caching layer replaced fragmented, per-thread caching, reducing operational complexity.

Conclusion and next steps

The cache stampede problem compounds in multi-tenant encryption systems: excess data key generation on the encrypt side degrades cache hit ratios on the decrypt side, creating a feedback loop of redundant KMS calls. The AWS-recommended hierarchical keyring pattern with DynamoDB provides a production-ready solution that integrates with the AWS Encryption SDK with minimal code changes. For regulated environments requiring additional control, a custom caching approach can deliver similar results.

If you operate a multi-tenant SaaS platform or a high-throughput system with per-tenant encryption requirements, consider these patterns to optimize your encryption costs and performance.

To get started, explore the following resources:

If you have questions or feedback about this post, leave a comment in the Comments section.


Maria Gutovsky

Maria Gutovsky

Maria is a Solutions Architect at AWS, based in Tel Aviv, Israel. She is part of the Database and Analytics Technical Field Community. In her free time, you will probably find her building a new character for a Dungeons and Dragons campaign.

Hemmy Yona

Hemmy Yona

Hemmy is a Solutions Architect at AWS, based in Israel. With 20 years of experience in software development and group management, Hemmy is passionate about helping customers build innovative, scalable, and cost-effective solutions. Outside of work, you’ll find Hemmy enjoying sports and traveling with family.

Contributor

Special thanks to Devora Roth Goldshmidt, Head of X-Sight Architects at NICE Actimize, who made a significant contribution to this post.

AWS partners with Anthropic and OpenAI to bring AWS Continuum into developer workflows

Post Syndicated from Chet Kapoor original https://aws.amazon.com/blogs/security/aws-partners-with-anthropic-and-openai-to-bring-aws-continuum-into-developer-workflows/

Customers have access to models that are continuously getting better with each new generation bringing larger context windows, stronger reasoning, and lower token costs. Getting the strongest AI-powered security will come from tools that combine the most relevant models with deep knowledge of a customer’s specific environment.

AWS Continuum for code vulnerabilities (Preview) is built to be that tool to help secure your code at machine speed. Today, we’re announcing a partnership with Anthropic and OpenAI that extends AWS Continuum directly into the developer workflows where code is being written: Anthropic Claude Code, OpenAI Codex, and Kiro. Developers can use these integrations to discover vulnerabilities, contextually prioritize, validate, and remediate, within their existing workflows.

Models are getting smarter

AI models are advancing rapidly. Each generation brings new capabilities, and different models excel at different tasks. The latest frontier models can now identify vulnerabilities and reason through multi-step attack paths that would take a human security team weeks to trace manually.

This is a genuine breakthrough in detection, but it creates a new challenge for your security teams: more findings, more complexity, and the need to determine which ones matter most in your environment and how to address them. The next challenge customers face is building the correct harness and orchestration to turn these models into a single interface that goes from detection through remediation. This is what we set out to do when creating Continuum, which brings together many different models and uses the model that’s most effective for each part of the process.

We also partner with the Frontier Model Forum, an industry consortium developing shared safety standards, evaluation methods, and benchmarking to ensure we can evaluate these models effectively together. We’re also working with model providers on shared security performance benchmarking to make sure we’re using the best model for each task within Continuum and our other AWS security products.

The harness

An AI harness is the orchestration layer that wraps around a model to connect it to tools, guardrails, memory, and workflows, so it delivers outcomes. Think of the model as the engine and the harness as everything around it. You need both to have a high-performance car.

Harnesses are becoming increasingly complex. Teams are stitching together multiple models, agents that call agents, and dynamic workflows, and are dealing with constant change driven by innovations in models, agent frameworks, and tool integrations.

As a result of that complexity, customers are implementing shadow infrastructure to manage integration layers across models and tools. Every time the landscape shifts, security and governance controls potentially break, forcing teams to go back to revisit them and make updates.

These challenges extend beyond the model. They arise in the orchestration required to connect different models and developer environments with tools, context, controls, and workflows across a customer’s environment. At AWS, we see managing that complexity as heavy lifting that AWS should solve. We treat the harness as infrastructure and with the same rigor we apply to identity, discovery, policy enforcement, observability, and compliance of the core infrastructure at AWS.

Enter Continuum

AWS Continuum for code vulnerabilities discovers vulnerabilities, prioritizes them within the context of a customer’s business, validates them in a sandbox, and provides remediation at machine speed. Under the hood, Continuum is an agent-team loop architecture. A sophisticated harness that orchestrates all of it: selecting the right model, connecting to a customer environment, and delivering secure code that’s been validated in context. You never need to think about how the orchestration works, or what changed in the latest release.

Anthropic and OpenAI partnerships

Today we’re announcing partnerships with Anthropic and OpenAI to bring Continuum into the developer workflows where code is being written.

How it works:

Within Claude Code, Codex, and Kiro coding environments, on-demand vulnerability scans identify potential issues and send findings to Continuum. Continuum prioritizes them within the context of the customer’s AWS environment (configurations, AWS Identity and Access Management (IAM) policies, network topology, and exposure surfaces) and validates them in a sandbox. It then returns prioritized, contextual intelligence back to the coding assistant, which adjusts its recommendations accordingly.

This collapses what was traditionally a multi-step, multi-team process (write, scan, triage, prioritize, fix, rescan) into a single outcome: the code suggestion itself. Two modes, one outcome:

  • For existing code: Use Continuum for code vulnerabilities from AWS to discover, prioritize, validate, and remediate across your environment.
  • For greenfield code: Use the Continuum plugin within Codex, Claude Code, or Kiro to get security-validated suggestions in your development environment.

Early design partners are already seeing results.

“AWS Continuum connects source code with enterprise knowledge, allowing teams to accurately pinpoint security vulnerabilities and verify that flagged issues are truly meaningful. This shortens what really matters: timeline to fix serious vulnerabilities.” – Mike Johnson, CISO, Rivian

Next

  • AWS Continuum for code vulnerabilities is available in preview through AWS. Sign up to request access at AWS Continuum.
  • Continuum integrated into Claude Code, Codex, and Kiro workflows are coming soon.

If you have feedback about this post, submit comments in the Comments section below.
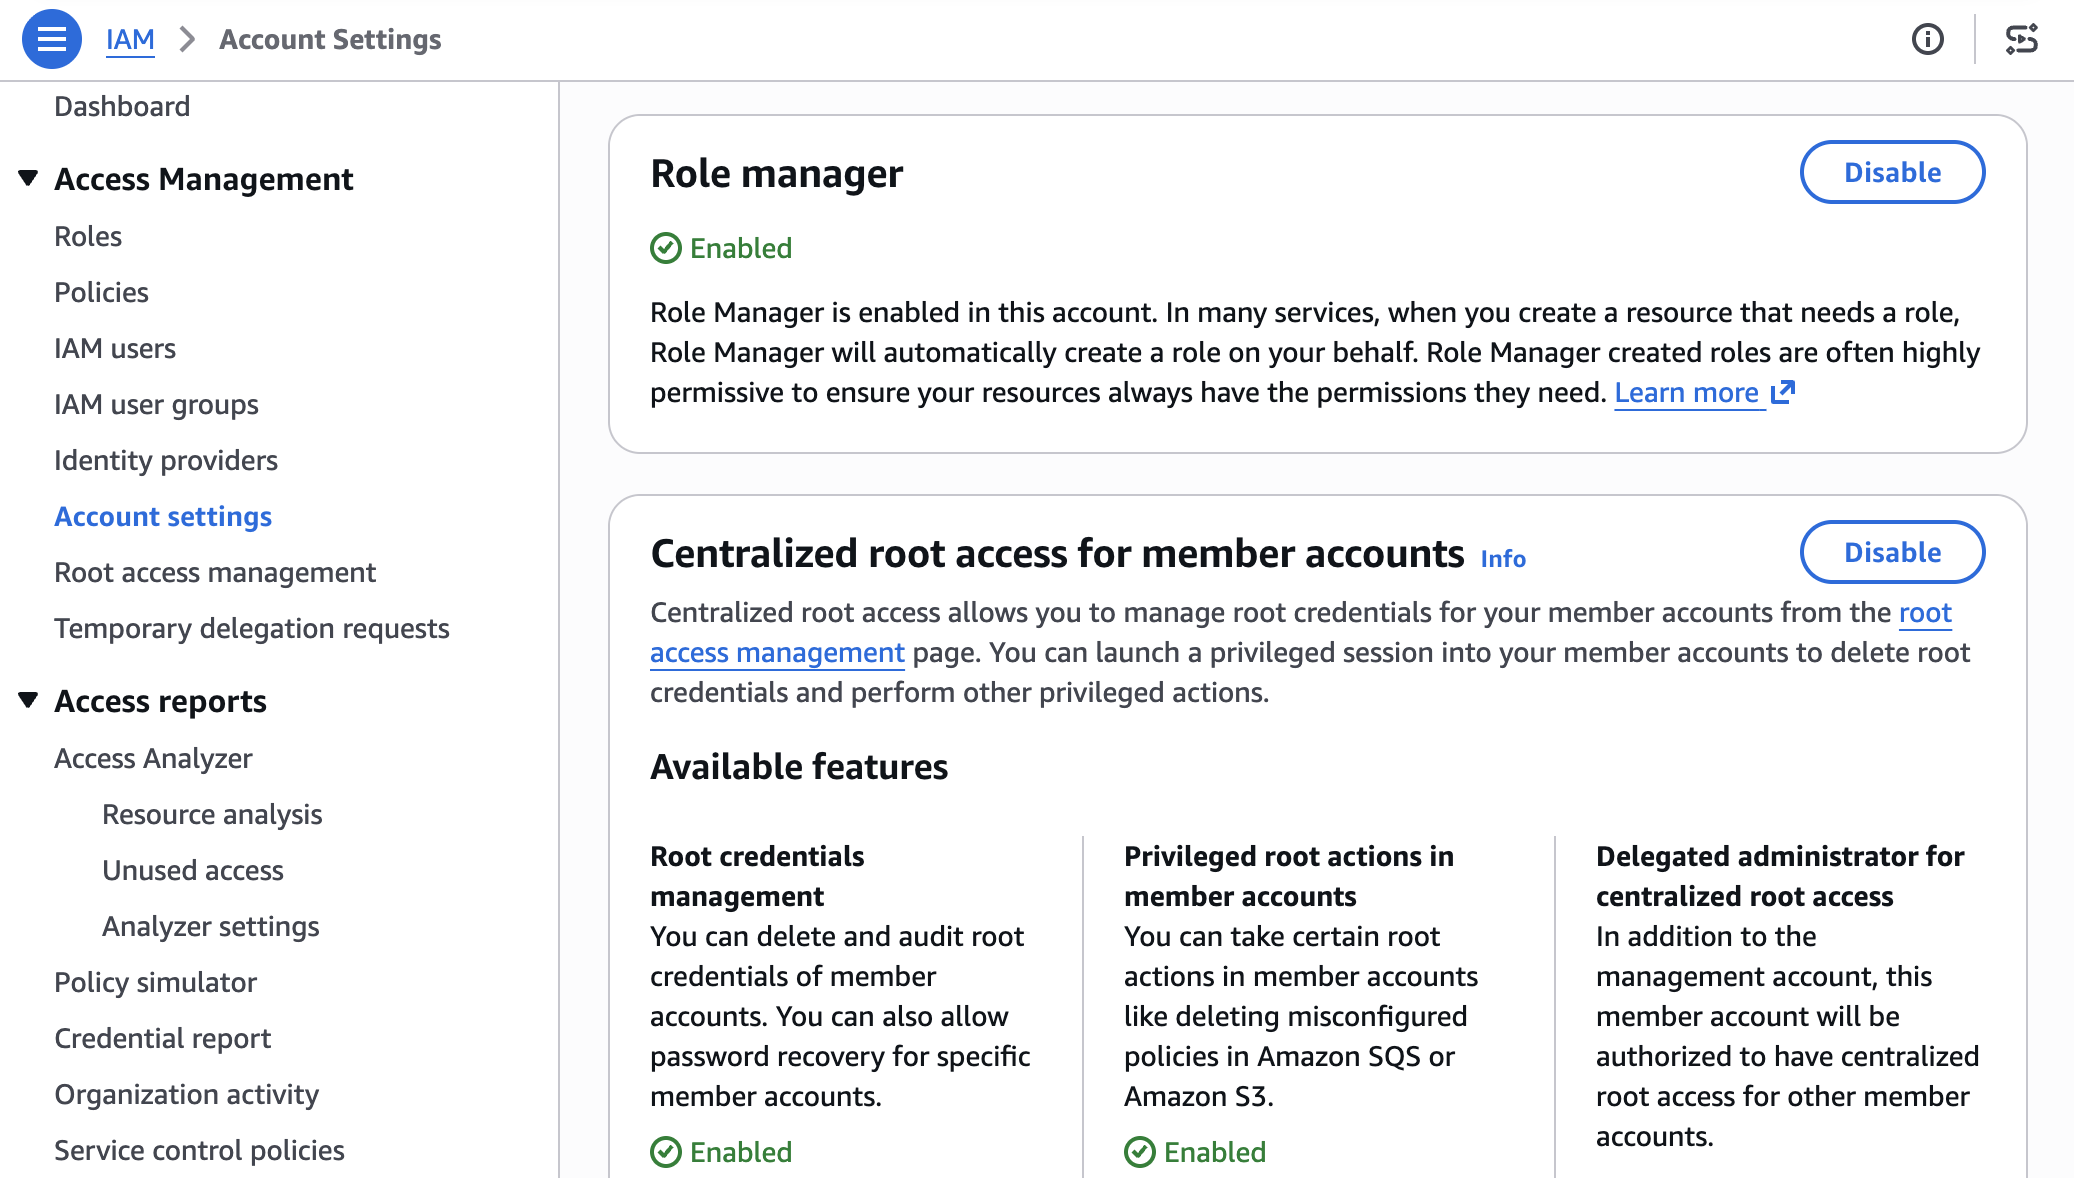

Chet Kapoor

Chet Kapoor

Chet is Vice President of Search, Security, and Observability at Amazon Web Services. With more than two decades in enterprise technology, he has led companies through some of the industry’s most consequential platform shifts — from APIs and open source to cloud and AI — building and scaling businesses through periods of rapid growth, transformation, acquisition, and IPO. He brings a builder’s mindset, deep operational experience, and a strong customer orientation to helping organizations adopt emerging technologies securely and at scale.

From 2 weeks to 2 minutes: Amazon Cognito launches Provisioned limits for self-service rate limit management

Post Syndicated from Kiran Dongara original https://aws.amazon.com/blogs/security/from-2-weeks-to-2-minutes-amazon-cognito-launches-provisioned-limits-for-self-service-rate-limit-management/

Imagine preparing for your biggest sales event of the year, and you want to ensure your customer identity management service can handle the elevated traffic for carrying out application activities. For security teams, business leaders, and technologists managing identity infrastructure at scale, this scenario has been all too familiar. Whether you’re a CISO evaluating security controls, a CFO managing cloud costs, traditional support ticket processes for adjusting Amazon Cognito rate limits meant waiting 10–14 days for capacity increases, requiring teams to plan weeks in advance or rush to escalate.

Today, we’re announcing provisioned limits for Amazon Cognito, a capability that transforms how you manage authentication rate limits. This introduces a feature in the AWS Management Console for Amazon Cognito for on-demand capacity adjustments, working alongside the existing account-level maximum limits in AWS Service Quotas. Together, they give you self-service control over your authentication infrastructure so you can scale up for Black Friday (or similar sales events), scale down after tax season, and optimize costs with unprecedented precision. What once took up to 2 weeks now happens in minutes.

In this post, you’ll learn how provisioned limits work, the relationship between account-level maximums and provisioned capacity, the cost implications and optimization strategies, and step-by-step implementation guidance. This capability fundamentally changes how you approach authentication capacity planning.

Manual processes that can’t keep pace

Identity management services open the front door to your application. When users can’t sign in, everything else stops. Amazon Cognito offers extremely flexible limit management: customers can request adjustments as granular as 1 request per second (RPS) for as short as 1 day. As customer demand for faster, self-service adjustments grew, we identified opportunities to address the following challenges:

  • Support tickets required for each rate limit change
  • 10–14 day approval timelines for standard review and processing
  • Advance planning needed weeks ahead of anticipated traffic spikes

For businesses with seasonal traffic, like tax preparation services that see 90% of annual authentication volume in March and April, or ecommerce platforms preparing for Black Friday, these factors meant teams had to plan capacity decisions well in advance with limited ability to adjust in the moment.

Provisioned limits and account-level max limits

Starting July 6, 2026, Amazon Cognito introduced provisioned limits in the Amazon Cognito console. At the account level (per AWS Region, per account), you’ll find a Provisioned limits tab next to the User Pools tab. This gives you direct control over your authentication rate limits through two complementary mechanisms:

  • Provisioned limits (Amazon Cognito console) – Adjust your provisioned capacity up or down on-demand. Changes take effect immediately. You’re billed for the capacity you provision above the default limit, regardless of how much you use.
  • Account-level max limit (Service Quotas console) – Set your account’s ceiling, the maximum RPS your account is allowed to provision. Raising this ceiling doesn’t incur additional charges. Approximately 90% of requests are automatically approved within minutes. For larger limit increases (depending on the API category and Region), manual approval through AWS Support might still be required.

The following experience shows the end-to-end workflow of adjusting your provisioned limits and requesting a higher account-level max.

Figure 1: Provisioned limit experience workflow

Figure 1: Provisioned limit experience workflow

How they work together

Let’s use the UserCreation API as an example. The default limit is 50 RPS, and initially the provisioned limit is also 50 RPS—meaning billed capacity is 0 (no additional charge). The applied account-level max limit is also 50 RPS. So you have three values: default (50), provisioned limit (50), and account-level max (50).

  1. Start by going to the Amazon Cognito console and choosing User pools from the navigation pane.

    Figure 2: UserCreation with default values

    Figure 2: UserCreation with default values

  2. Choose Edit provisioned limit, to go to the Edit provisioned limit page with an input field for New provisioned limit. However, because the account-level max limit is 50 RPS, you can’t set the provisioned limit above 50. For example, if you want to provision 55 RPS, the console won’t allow it because 55 exceeds the current account max of 50.

    Figure 3: Editing the provisioned limit constraint constraint to more than the account-level max

    Figure 3: Editing the provisioned limit constraint constraint to more than the account-level max

  3. To set a higher limit, choose Request an increase. This takes you to the Service Quotas console, where you can choose Request increase at account level to request a higher account-level max, for example, 55 RPS. Most requests are automatically approved within minutes. At any time, you can check the status of the request using the Request history tab.

    Figure 4: Service Quotas page where the account-level max increase is requested and auto-approved

    Figure 4: Service Quotas page where the account-level max increase is requested and auto-approved

  4. After receiving approval, return to the Amazon Cognito console to edit your provisioned limit up to 55 RPS. Your billed capacity becomes 5 RPS (55 minus the 50 default).

    Figure 5: Provisioned after increasing the provisioned limit to 55 RPS, with billed capacity of 5 RPS.

    Figure 5: Provisioned after increasing the provisioned limit to 55 RPS, with billed capacity of 5 RPS.

This two-part model gives you precise control over both cost and capacity. Raising the account-level max in Service Quotas doesn’t incur additional charges—it only sets your ceiling. You are billed for what you provision in the Amazon Cognito console above the default, so you benefit from right-sizing your provisioned capacity to match expected demand. Raise your account max ahead of time to prepare for future scaling needs without incurring any cost. When the time comes, increase your provisioned limit to what you need, and scale back down after the event. You stop being charged for the extra capacity as soon as you reduce the provisioned limit. This applies equally to seasonal spikes, planned load tests, or unexpected viral growth—all self-service, all within minutes.

How the provisioned limits experience works

The provisioned limits experience introduces three key concepts that work together:

  • Default limit – The baseline rate included at no additional cost (for example, 50 RPS for UserCreation).
  • Provisioned limit – The capacity you actively request and reserve in the Amazon Cognito console. Because this capacity is reserved specifically for your account, it’s the chargeable dimension. You’re billed for any provisioned capacity above the default, regardless of how much you consume. For example, if the default is 50 RPS and you provision 80 RPS, you’re billed for 30 RPS even if your actual usage is only 60 RPS. If your provisioned capacity is 50 RPS (the default), your billed capacity is 0.
  • Applied account-level max limit – The ceiling managed through Service Quotas. This determines how high you can set your provisioned limit. Raising this ceiling doesn’t incur charges, it only unlocks the ability to provision higher capacity. Importantly, the Provisioned limits page displays each API category with its adjustability status. For example, UserCreation is marked Adjustable (shown earlier in Figure 5) and can be modified. However, UserList is marked Not adjustable, meaning the account-level max limit can’t be adjusted for that category. You can still see its default and provisioned limit on the page, but you can’t modify them. For adjustable categories, you will see the default limit, current provisioned limit, and billed capacity at a glance.
Figure 6: Provisioned limits overview with non-adjustable API categories.

Figure 6: Provisioned limits overview with non-adjustable API categories.

Multi-tenant SaaS considerations

For software as a service (SaaS) providers managing multiple tenants with varying throughput requirements, the UpdateProvisionedLimit API enables programmatic management of provisioned capacity. Teams using dedicated user pools per tenant, for example, can integrate this into their infrastructure-as-code pipelines to adjust provisioned limits per tenant tier. With provisioned limits, SaaS vendors can tier their capacity management per tenant, for example, provisioning higher capacity for enterprise-tier tenants and lower capacity for free-tier tenants, and adjust each tenant’s provisioned capacity independently through the API based on their service tier and demand patterns.

Conclusion

With provisioned limits, whether you’re preparing for peak shopping season, tax filing deadlines, or any other scaling event, you can now adjust provisioned limits to respond to your organization’s needs on demand. The separation between the account-level max (in Service Quotas) and the provisioned limit (in the Amazon Cognito console) gives you full control to plan ahead, respond to demand changes in minutes, and optimize costs on your own terms.

Get started

The provisioned limits experience for Amazon Cognito user pools launched on July 6, 2026, and is available across all AWS Regions where Amazon Cognito is supported. To get started:

  1. Review your current authentication traffic patterns using Amazon CloudWatch metrics to understand your baseline
  2. Set up CloudWatch alarms at 70% and 85% of your current rate limits
  3. Ensure your team has appropriate AWS Identity and Access Management ( IAM) permissions for both Service Quotas and the Provisioned limits tab in the Amazon Cognito console
  4. Raise your account-level max in Service Quotas based on your demand expectations
  5. Use the Amazon Cognito console Provisioned limits tab to adjust capacity up or down as needed

Resources:

Need help? Contact your AWS account team or visit AWS Support for assistance with planning your rate limit strategy.

If you have feedback about this post, submit comments in the Comments section below.
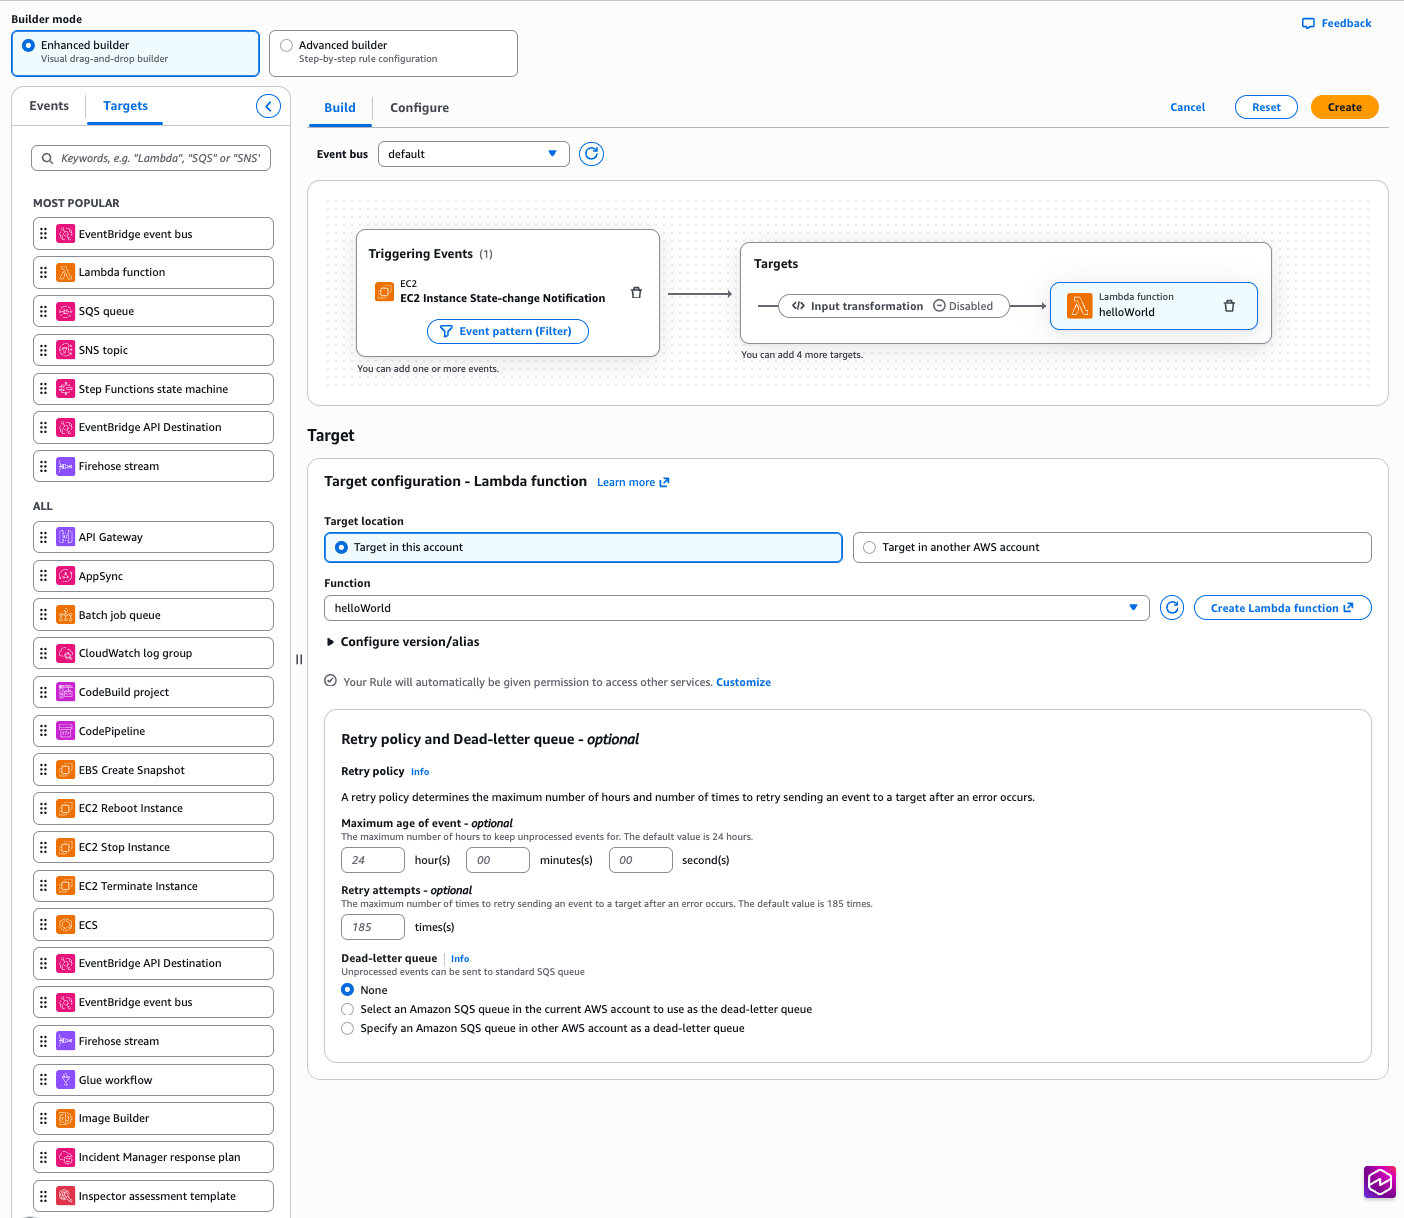

Kiran Dongara

Kiran is an Enterprise Solutions Architect at AWS, primarily supporting Retail, Restaurant, and CPG customers. His primary focus is application identity within the IAM domain. His expertise includes deep technical understanding across technical and industry domains, which he integrates to design scalable and efficient architectures using best practices. When not working, Kiran prioritizes family time, nature walks, and cycling.

Howie Li

Howie Li

Howie Li is a Product Manager at Amazon Web Services, where he strives to make authentication straightforward by default. Outside of work, Howie enjoys exploring cultures and food through travels and making new ice cream flavors inspired by them.