Tag Archives: Uncategorized

Apple Mail Now Blocks Email Trackers

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/05/apple-mail-now-blocks-email-trackers.html

Apple Mail now blocks email trackers by default.

Most email newsletters you get include an invisible “image,” typically a single white pixel, with a unique file name. The server keeps track of every time this “image” is opened and by which IP address. This quirk of internet history means that marketers can track exactly when you open an email and your IP address, which can be used to roughly work out your location.

So, how does Apple Mail stop this? By caching. Apple Mail downloads all images for all emails before you open them. Practically speaking, that means every message downloaded to Apple Mail is marked “read,” regardless of whether you open it. Apples also routes the download through two different proxies, meaning your precise location also can’t be tracked.

Crypto-Gram uses Mailchimp, which has these tracking pixels turned on by default. I turn them off. Normally, Mailchimp requires them to be left on for the first few mailings, presumably to prevent abuse. The company waived that requirement for me.

Friday Squid Blogging: Squid Filmed Changing Color for Camouflage Purposes

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/05/friday-squid-blogging-squid-filmed-changing-color-for-camouflage-purposes.html

Video of oval squid (Sepioteuthis lessoniana) changing color in reaction to their background. The research paper claims this is the first time this has been documented.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

Throttling a tiered, multi-tenant REST API at scale using API Gateway: Part 1

Post Syndicated from Nick Choi original https://aws.amazon.com/blogs/architecture/throttling-a-tiered-multi-tenant-rest-api-at-scale-using-api-gateway-part-1/

Many software-as-a-service (SaaS) providers adopt throttling as a common technique to protect a distributed system from spikes of inbound traffic that might compromise reliability, reduce throughput, or increase operational cost. Multi-tenant SaaS systems have an additional concern of fairness; excessive traffic from one tenant needs to be selectively throttled without impacting the experience of other tenants. This is also known as “the noisy neighbor” problem. AWS itself enforces some combination of throttling and quota limits on nearly all its own service APIs. SaaS providers building on AWS should design and implement throttling strategies in all of their APIs as well.

In this two-part blog series, we will explore tiering and throttling strategies for multi-tenant REST APIs and review tenant isolation models with hands-on sample code. In part 1, we will look at why a tiering and throttling strategy is needed and show how Amazon API Gateway can help by showing sample code. In part 2, we will dive deeper into tenant isolation models as well as considerations for production.

We selected Amazon API Gateway for this architecture since it is a fully managed service that helps developers to create, publish, maintain, monitor, and secure APIs. First, let’s focus on how Amazon API Gateway can be used to throttle REST APIs with fine granularity using Usage Plans and API Keys. Usage Plans define the thresholds beyond which throttling should occur. They also enable quotas, which sets a maximum usage per a day, week, or month. API Keys are identifiers for distinguishing traffic and determining which Usage Plans to apply for each request. We limit the scope of our discussion to REST APIs because other protocols that API Gateway supports — WebSocket APIs and HTTP APIs — have different throttling mechanisms that do not employ Usage Plans or API Keys.

SaaS providers must balance minimizing cost to serve and providing consistent quality of service for all tenants. They also need to ensure one tenant’s activity does not affect the other tenants’ experience. Throttling and quotas are a key aspect of a tiering strategy and important for protecting your service at any scale. In practice, this impact of throttling polices and quota management is continuously monitored and evaluated as the tenant composition and behavior evolve over time.

Architecture Overview

Figure 1. Cloud Architecture of the sample code.

Figure 1 – Architecture of the sample code

To get a firm foundation of the basics of throttling and quotas with API Gateway, we’ve provided sample code in AWS-Samples on GitHub. Not only does it provide a starting point to experiment with Usage Plans and API Keys in the API Gateway, but we will modify this code later to address complexity that happens at scale. The sample code has two main parts: 1) a web frontend and, 2) a serverless backend. The backend is a serverless architecture using Amazon API Gateway, AWS Lambda, Amazon DynamoDB, and Amazon Cognito. As Figure I illustrates, it implements one REST API endpoint, GET /api, that is protected with throttling and quotas. There are additional APIs under the /admin/* resource to provide Read access to Usage Plans, and CRUD operations on API Keys.

All these REST endpoints could be tested with developer tools such as curl or Postman, but we’ve also provided a web application, to help you get started. The web application illustrates how tenants might interact with the SaaS application to browse different tiers of service, purchase API Keys, and test them. The web application is implemented in React and uses AWS Amplify CLI and SDKs.

Prerequisites

To deploy the sample code, you should have the following prerequisites:

For clarity, we’ll use the environment variable, ${TOP}, to indicate the top-most directory in the cloned source code or the top directory in the project when browsing through GitHub.

Detailed instructions on how to install the code are in ${TOP}/INSTALL.md file in the code. After installation, follow the ${TOP}/WALKTHROUGH.md for step-by-step instructions to create a test key with a very small quota limit of 10 requests per day, and use the client to hit that limit. Search for HTTP 429: Too Many Requests as the signal your client has been throttled.

Figure 2: The web application (with browser developer tools enabled) shows that a quick succession of API calls starts returning an HTTP 429 after the quota for the day is exceeded.

Figure 2: The web application (with browser developer tools enabled) shows that a quick succession of API calls starts returning an HTTP 429 after the quota for the day is exceeded.

Responsibilities of the Client to support Throttling

The Client must provide an API Key in the header of the HTTP request, labelled, “X-Api-Key:”. If a resource in API Gateway has throttling enabled and that header is missing or invalid in the request, then API Gateway will reject the request.

Important: API Keys are simple identifiers, not authorization tokens or cryptographic keys. API keys are for throttling and managing quotas for tenants only and not suitable as a security mechanism. There are many ways to properly control access to a REST API in API Gateway, and we refer you to the AWS documentation for more details as that topic is beyond the scope of this post.

Clients should always test for the response to any network call, and implement logic specific to an HTTP 429 response. The correct action is almost always “try again later.” Just how much later, and how many times before giving up, is application dependent. Common approaches include:

  • Retry – With simple retry, client retries the request up to defined maximum retry limit configured
  • Exponential backoff – Exponential backoff uses progressively larger wait time between retries for consecutive errors. As the wait time can become very long quickly, maximum delay and a maximum retry limits should be specified.
  • Jitter – Jitter uses a random amount of delay between retry to prevent large bursts by spreading the request rate.

AWS SDK is an example client-responsibility implementation. Each AWS SDK implements automatic retry logic that uses a combination of retry, exponential backoff, jitter, and maximum retry limit.

SaaS Considerations: Tenant Isolation Strategies at Scale

While the sample code is a good start, the design has an implicit assumption that API Gateway will support as many API Keys as we have number of tenants. In fact, API Gateway has a quota on available per region per account. If the sample code’s requirements are to support more than 10,000 tenants (or if tenants are allowed multiple keys), then the sample implementation is not going to scale, and we need to consider more scalable implementation strategies.

This is one instance of a general challenge with SaaS called “tenant isolation strategies.” We highly recommend reviewing this white paper ‘SasS Tenant Isolation Strategies‘. A brief explanation here is that the one-resource-per-customer (or “siloed”) model is just one of many possible strategies to address tenant isolation. While the siloed model may be the easiest to implement and offers strong isolation, it offers no economy of scale, has high management complexity, and will quickly run into limits set by the underlying AWS Services. Other models besides siloed include pooling, and bridged models. Again, we recommend the whitepaper for more details.

Figure 3. Tiered multi-tenant architectures often employ different tenant isolation strategies at different tiers. Our example is specific to API Keys, but the technique generalizes to storage, compute, and other resources.

Figure 3- Tiered multi-tenant architectures often employ different tenant isolation strategies at different tiers. Our example is specific to API Keys, but the technique generalizes to storage, compute, and other resources.

In this example, we implement a range of tenant isolation strategies at different tiers of service. This allows us to protect against “noisy-neighbors” at the highest tier, minimize outlay of limited resources (namely, API-Keys) at the lowest tier, and still provide an effective, bounded “blast radius” of noisy neighbors at the mid-tier.

A concrete development example helps illustrate how this can be implemented. Assume three tiers of service: Free, Basic, and Premium. One could create a single API Key that is a pooled resource among all tenants in the Free Tier. At the other extreme, each Premium customer would get their own unique API Key. They would protect Premium tier tenants from the ‘noisy neighbor’ effect. In the middle, the Basic tenants would be evenly distributed across a set of fixed keys. This is not complete isolation for each tenant, but the impact of any one tenant is contained within “blast radius” defined.

In production, we recommend a more nuanced approach with additional considerations for monitoring and automation to continuously evaluate tiering strategy. We will revisit these topics in greater detail after considering the sample code.

Conclusion

In this post, we have reviewed how to effectively guard a tiered multi-tenant REST API hosted in Amazon API Gateway. We also explored how tiering and throttling strategies can influence tenant isolation models. In Part 2 of this blog series, we will dive deeper into tenant isolation models and gaining insights with metrics.

If you’d like to know more about the topic, the AWS Well-Architected SaaS Lens Performance Efficiency pillar dives deep on tenant tiers and providing differentiated levels of performance to each tier. It also provides best practices and resources to help you design and reduce impact of noisy neighbors your SaaS solution.

To learn more about Serverless SaaS architectures in general, we recommend the AWS Serverless SaaS Workshop and the SaaS Factory Serverless SaaS reference solution that inspired it.

Corporate Involvement in International Cybersecurity Treaties

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/05/corporate-involvement-in-international-cybersecurity-treaties.html

The Paris Call for Trust and Stability in Cyberspace is an initiative launched by French President Emmanuel Macron during the 2018 UNESCO’s Internet Governance Forum. It’s an attempt by the world’s governments to come together and create a set of international norms and standards for a reliable, trustworthy, safe, and secure Internet. It’s not an international treaty, but it does impose obligations on the signatories. It’s a major milestone for global Internet security and safety.

Corporate interests are all over this initiative, sponsoring and managing different parts of the process. As part of the Call, the French company Cigref and the Russian company Kaspersky chaired a working group on cybersecurity processes, along with French research center GEODE. Another working group on international norms was chaired by US company Microsoft and Finnish company F-Secure, along with a University of Florence research center. A third working group’s participant list includes more corporations than any other group.

As a result, this process has become very different than previous international negotiations. Instead of governments coming together to create standards, it is being drive by the very corporations that the new international regulatory climate is supposed to govern. This is wrong.

The companies making the tools and equipment being regulated shouldn’t be the ones negotiating the international regulatory climate, and their executives shouldn’t be named to key negotiation roles without appointment and confirmation. It’s an abdication of responsibility by the US government for something that is too important to be treated this cavalierly.

On the one hand, this is no surprise. The notions of trust and stability in cyberspace are about much more than international safety and security. They’re about market share and corporate profits. And corporations have long led policymakers in the fast-moving and highly technological battleground that is cyberspace.

The international Internet has always relied on what is known as a multistakeholder model, where those who show up and do the work can be more influential than those in charge of governments. The Internet Engineering Task Force, the group that agrees on the technical protocols that make the Internet work, is largely run by volunteer individuals. This worked best during the Internet’s era of benign neglect, where no one but the technologists cared. Today, it’s different. Corporate and government interests dominate, even if the individuals involved use the polite fiction of their own names and personal identities.

However, we are a far cry from decades past, where the Internet was something that governments didn’t understand and largely ignored. Today, the Internet is an essential infrastructure that underpins much of society, and its governance structure is something that nations care about deeply. Having for-profit tech companies run the Paris Call process on regulating tech is analogous to putting the defense contractors Northrop Grumman or Boeing in charge of the 1970s SALT nuclear agreements between the US and the Soviet Union.

This also isn’t the first time that US corporations have led what should be an international relations process regarding the Internet. Since he first gave a speech on the topic in 2017, Microsoft President Brad Smith has become almost synonymous with the term “Digital Geneva Convention.” It’s not just that corporations in the US and elsewhere are taking a lead on international diplomacy, they’re framing the debate down to the words and the concepts.

Why is this happening? Different countries have their own problems, but we can point to three that currently plague the US.

First and foremost, “cyber” still isn’t taken seriously by much of the government, specifically the State Department. It’s not real to the older military veterans, or to the even older politicians who confuse Facebook with TikTok and use the same password for everything. It’s not even a topic area for negotiations for the US Trade Representative. Nuclear disarmament is “real geopolitics,” while the Internet is still, even now, seen as vaguely magical, and something that can be “fixed” by having the nerds yank plugs out of a wall.

Second, the State Department was gutted during the Trump years. It lost many of the up-and-coming public servants who understood the way the world was changing. The work of previous diplomats to increase the visibility of the State Department’s cyber efforts was abandoned. There are few left on staff to do this work, and even fewer to decide if they’re any good. It’s hard to hire senior information security professionals in the best of circumstances; it’s why charlatans so easily flourish in the cybersecurity field. The built-up skill set of the people who poured their effort and time into this work during the Obama years is gone.

Third, there’s a power struggle at the heart of the US government involving cyber issues, between the White House, the Department of Homeland Security (represented by CISA), and the military (represented by US Cyber Command). Trying to create another cyber center of power within the State Department threatens those existing powers. It’s easier to leave it in the hands of private industry, which does not affect those government organizations’ budgets or turf.

We don’t want to go back to the era when only governments set technological standards. The governance model from the days of the telephone is another lesson in how not to do things. The International Telecommunications Union is an agency run out of the United Nations. It is moribund and ponderous precisely because it is run by national governments, with civil society and corporations largely alienated from the decision-making processes.

Today, the Internet is fundamental to global society. It’s part of everything. It affects national security and will be a theater in any future war. How individuals, corporations, and governments act in cyberspace is critical to our future. The Internet is critical infrastructure. It provides and controls access to healthcare, space, the military, water, energy, education, and nuclear weaponry. How it is regulated isn’t just something that will affect the future. It is the future.

Since the Paris Call was finalized in 2018, it has been signed by 81 countries — including the US in 2021 — 36 local governments and public authorities, 706 companies and private organizations, and 390 civil society groups. The Paris Call isn’t the first international agreement that puts companies on an equal signatory footing as governments. The Global Internet Forum to Combat Terrorism and the Christchurch Call to eliminate extremist content online do the same thing. But the Paris Call is different. It’s bigger. It’s more important. It’s something that should be the purview of governments and not a vehicle for corporate power and profit.

When something as important as the Paris Call comes along again, perhaps in UN negotiations for a cybercrime treaty, we call for actual State Department officials with technical expertise to be sitting at the table with the interests of the entire US in their pocket…not people with equity shares to protect.

This essay was written with Tarah Wheeler, and previously published on The Cipher Brief.

Orchestrating Amazon S3 Glacier Deep Archive object retrieval using AWS Step Functions

Post Syndicated from Eric Johnson original https://aws.amazon.com/blogs/compute/orchestrating-amazon-s3-glacier-deep-archive-object-retrieval-using-aws-step-functions/

This blog was written by Monica Cortes Sack, Solutions Architect, Oskar Neumann, Partner Solutions Architect, and Dhiraj Mahapatro, Principal Specialist SA, Serverless.

AWS Step Functions now support over 220 services and over 10,000 AWS API actions. This enables you to use the AWS SDK integration directly instead of writing an AWS Lambda function as a proxy.

One such service integration is with Amazon S3. Currently, you write scripts using AWS CLI S3 commands to achieve automation around running S3 tasks. For example, S3 integrates with AWS Transfer Family, builds a custom security check, takes action on S3 buckets on S3 object creations, or orchestrates a workflow around S3 Glacier Deep Archive object retrieval. These script executions do not provide an execution history or an easy way to validate the behavior.

Step Functions’ AWS SDK integration with S3 declaratively creates serverless workflows around S3 tasks without relying on those scripts. You can validate the execution history and behavior of a Step Functions workflow.

This blog highlights one of the S3 use cases. It shows how to orchestrate workflows around S3 Glacier Deep Archive object retrieval, cost estimation, and interaction with the requester using Step Functions. The demo application provides additional details on the entire architecture.

S3 Glacier Deep Archive is a storage class in S3 used for data that is rarely accessed. The service provides durable and secure long-term storage, trading immediate access for cost-effectiveness. You must restore archived objects before they are downloadable. It supports two options for object retrieval:

  1. Standard – Access objects within 12 hours of the start of the restoration process.
  2. Bulk – Access objects within 48 hours of the start of the restoration process.

Business use case

Consider a research institute that stores backups on S3 Glacier Deep Archive. The backups are maintained in S3 Glacier Deep Archive for redundancy. The institute has multiple researchers with one central IT team. When a researcher requests an object from S3 Glacier Deep Archive, the central IT team retrieves it and charges the corresponding research group for retrieval and data transfer costs.

Researchers are the end users and do not operate in the AWS Cloud. They run computing clusters on-premises and depend on the central IT team to provide them with the restored archive. A member of the research team requesting an object retrieval provides the following information to the central IT team:

  1. Object key to be restored.
  2. The number of days the researcher needs the object accessible for download.
  3. Researcher’s email address.
  4. Retrieve within 12 or 48 hours SLA. This determines whether “Standard” or “Bulk” retrieval respectively.

The following overall architecture explains the setup on AWS and the interaction between a researcher and the central IT team’s architecture.

Architecture overview

Architecture diagram

Architecture diagram

  1. The researcher uses a front-end application to request object retrieval from S3 Glacier Deep Archive.
  2. Amazon API Gateway synchronously invokes AWS Step Functions Express Workflow.
  3. Step Functions initiates RestoreObject from S3 Glacier Deep Archive.
  4. Step Functions stores the metadata of this retrieval in an Amazon DynamoDB table.
  5. Step Functions uses Amazon SES to email the researcher about archive retrieval initiation.
  6. Upon completion, S3 sends the RestoreComplete event to Amazon EventBridge.
  7. EventBridge rule triggers another Step Functions for post-processing after the restore is complete.
  8. A Lambda function inside the Step Functions calculates the estimated cost (retrieval and data transfer out) and updates existing metadata in the DynamoDB table.
  9. Sync data from DynamoDB table using Amazon Athena Federated Queries to generate reports dashboard in Amazon QuickSight.
  10. Step Functions uses SES to email the researcher with cost details.
  11. Once the researcher receives an email, the researcher uses the front-end application to call the /download API endpoint.
  12. API Gateway invokes a Lambda function that generates a pre-signed S3 URL of the retrieved object and returns it in the response.

Setup

  1. To run the sample application, you must install CDK v2, Node.js, and npm.
  2. To clone the repository, run:
    git clone https://github.com/aws-samples/aws-stepfunctions-examples.git
    cd cdk/app-glacier-deep-archive-retrieval
  3. To deploy the application, run:
    cdk deploy --all

Identifying workflow components

Starting the restore object workflow

The first component is accepting the researcher’s request to start the archive retrieval process. The sample application created from the demo provides a basic front-end app that shows the files from an S3 bucket that has objects stored in S3 Glacier Deep Archive. The researcher retrieves file requests from the front-end application reached by the sample application’s Amazon CloudFront URL.

Glacier Deep Archive Retrieval menu

Glacier Deep Archive Retrieval menu

The front-end app asks the researcher for an email address, the number of days the researcher wants the object to be available for download, and their ETA on retrieval speed. Based on the retrieval speed, the researcher accepts either Standard or Bulk object retrieval. To test this, put objects in the data bucket under the S3 Glacier Deep Archive storage class and use the front-end application to retrieve them.

Item retrieval prompt

Item retrieval prompt

The researcher then chooses the Retrieve file. This action invokes an API endpoint provided by API Gateway. The API Gateway endpoint synchronously invokes a Step Functions Express Workflow. This validates the restore object request, gets the object metadata, and starts to restore the object from S3 Glacier Deep Archive.

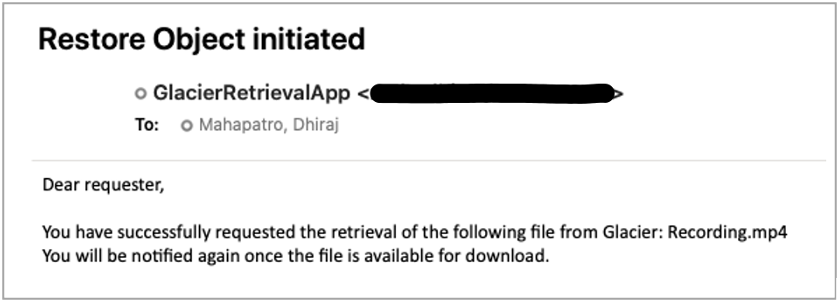
The state machine stores the metadata of the restore object AWS SDK call in a DynamoDB table for later use. You can use this metadata to build a dashboard in Amazon QuickSight for reporting and administration purposes. Finally, the state machine uses Amazon SES to email the researcher, notifying them about the restore object initiation process:

Restore object initiated

Restore object initiated

The following state machine shows the workflow:

Workflow diagram

Workflow diagram

The ability to use S3 APIs declaratively using AWS SDK from Step Functions makes it convenient to integrate with S3. This approach avoids writing a Lambda function to wrap the SDK calls. The following portion of the state machine definition shows the usage of S3 HeadObject and RestoreObject APIs:

"Get Object Metadata": {
    "Next": "Initiate Restore Object from Deep Archive",
    "Catch": [{
        "ErrorEquals": ["States.ALL"],
        "Next": "Bad Request"
    }],
    "Type": "Task",
    "ResultPath": "$.result.metadata",
    "Resource": "arn:aws:states:::aws-sdk:s3:headObject",
    "Parameters": {
        "Bucket": "glacierretrievalapp-databucket-abc123",
        "Key.$": "$.fileKey"
    }
}, 
"Initiate Restore Object from Deep Archive": {
    "Next": "Update restore operation metadata",
    "Type": "Task",
    "ResultPath": null,
    "Resource": "arn:aws:states:::aws-sdk:s3:restoreObject",
    "Parameters": {
        "Bucket": "glacierretrievalapp-databucket-abc123",
        "Key.$": "$.fileKey",
        "RestoreRequest": {
            "Days.$": "$.requestedForDays"
        }
    }
}

You can extend the previous workflow and build your own Step Functions workflows to orchestrate other S3 related workflows.

Processing after object restoration completion

S3 RestoreObject is a long-running process for S3 Glacier Deep Archive objects. S3 emits a RestoreCompleted event notification on the object restore completion to EventBridge. You set up an EventBridge rule to trigger another Step Functions workflow as a target for this event. This workflow takes care of the object restoration post-processing.

cfnDataBucket.addPropertyOverride('NotificationConfiguration.EventBridgeConfiguration.EventBridgeEnabled', true);

An EventBridge rule triggers the following Step Functions workflow and passes the event payload as an input to the Step Functions execution:

new aws_events.Rule(this, 'invoke-post-processing-rule', {
  eventPattern: {
    source: ["aws.s3"],
    detailType: [
      "Object Restore Completed"
    ],
    detail: {
      bucket: {
        name: [props.dataBucket.bucketName]
      }
    }
  },
  targets: [new aws_events_targets.SfnStateMachine(this.stateMachine, {
    input: aws_events.RuleTargetInput.fromObject({
      's3Event': aws_events.EventField.fromPath('$')
    })
  })]
});

The Step Functions workflow gets object metadata from the DynamoDB table and then invokes a Lambda function to calculate the estimated cost. The Lambda function calculates the estimated retrieval and the data transfer costs using the contentLength of the retrieved object and the Price List API for the unit cost. The workflow then updates the calculated cost in the DynamoDB table.

The retrieval cost and the data transfer out cost are proportional to the size of the retrieved object. The Step Functions workflow also invokes a Lambda function to create the download API URL for object retrieval. Finally, it emails the researcher with the estimated cost and the download URL as a restoration completion notification.

Workflow studio diagram

Workflow studio diagram

The email notification to the researcher looks like:

Email example

Email example

Downloading the restored object

Once the object restoration is complete, the researcher can download the object from the front-end application.

Front end retrieval menu

Front end retrieval menu

The researcher chooses the Download action, which invokes another API Gateway endpoint. The endpoint integrates with a Lambda function as a backend that creates a pre-signed S3 URL sent as a response to the browser.

Administering object restoration usage

This architecture also provides a view for the central IT team to understand object restoration usage. You achieve this by creating reports and dashboards from the metadata stored in DynamoDB.

The sample application uses Amazon Athena Federated Queries and Amazon Athena DynamoDB Connector to generate a reports dashboard in Amazon QuickSight. You can also use Step Functions AWS SDK integration with Amazon Athena and visualize the workflows in the Athena console.

The following QuickSight visualization shows the count of restored S3 Glacier Deep Archive objects by their contentType:

QuickSite visualization

QuickSight visualization

Considerations

With the preceding approach, you should consider that:

  1. You must start the object retrieval in the same Region as the Region of the archived object.
  2. S3 Glacier Deep Archive only supports standard and bulk retrievals.
  3. You must enable the “Object Restore Completed” event notification on the S3 bucket with the S3 Glacier Deep Archive object.
  4. The researcher’s email must be verified in SES.
  5. Use a Lambda function for the Price List GetProducts API as the service endpoints are available in specific Regions.

Cleanup

To clean up the infrastructure used in this sample application, run:

cdk destroy --all

Conclusion

Step Functions’ AWS SDK integration opens up different opportunities to orchestrate a workflow. Step Functions provides native support for retries and error handling, which offloads the heavy lifting of handling them manually in scripts.

This blog shows one example use case with S3 Glacier Deep Archive. With AWS SDK integration in Step Functions, you can build any workflow orchestration using S3 or S3 control APIs. For example, a workflow to enforce AWS Key Management Service encryption based on an S3 event, or create static website hosting on-demand in a few steps.

With different S3 API calls available in Step Functions’ Workflow Studio, you can declaratively build a Step Functions workflow instead of imperatively calling each S3 API from a shell script or command line. Refer to the demo application for more details.

For more serverless learning resources, visit Serverless Land.

Amazon EC2 DL1 instances Deep Dive

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/amazon-ec2-dl1-instances-deep-dive/

This post is written by Amr Ragab, Principal Solutions Architect, Amazon EC2.

AWS is excited to announce that the new Amazon Elastic Compute Cloud (Amazon EC2) DL1 instances are now generally available in US-East (N. Virginia) and US-West (Oregon). DL1 provides up to 40% better price performance for training deep learning models as compared to current generation GPU-based EC2 instances. The dl1.24xlarge instance type features eight Intel-Habana Gaudi accelerators, which are custom-built to train deep learning models. Each Gaudi accelerator has 32 GB of high bandwidth memory (HBM2) and a peer-to-peer bidirectional bandwidth of 100 Gbps RoCE, for a total bidirectional interconnect bandwidth of 700 Gbps per card. Further instance specifications are as follows:

Instance Size vCPU Instance Memory (GiB) Gaudi Accelerators Network Bandwidth (Gbps) Total Accelerator Interconnect (Gbs) Local Instance Storage EBS Bandwidth (Gbps)
d1.24xlarge 96 768 8 4×100 Gbps 700 4x1TB NVMe 19

Instance Architecture

System architecture of the amazon ec2 dl1 instances.

As the preceding instance architecture indicates, pairs of Gaudi accelerators (e.g., Gaudi0 and Gaudi1) are attached directly through a PCIe Gen3x16 link. Additionally, peer-to-peer networking via 100 Gbps RoCEv2 links – with seven active links per card – provides a torus configuration with a total of 700 Gbps of interconnect bandwidth per card. This topology is a separate interconnect outside of the two NUMA domains. Furthermore, the instance supports four EFA ENIs and 4x1TB of local NVMe SSD storage. We will provide a peer-direct driver over EFA, which will let you utilize high throughput, low latency peer-direct networking between accelerators across multiple instances to efficiently scale multi-node distributed training workloads.

Quick Start

Quickly get started with DL1 and SynapseAI SDK through with the following options:

1) Habana Deep Learning AMIs provided by AWS.

2) AWS Marketplace AMIs provided by Habana.

3) Using Packer to build a custom Amazon Machine Images (AMI) provided by this GitHub repo. This repo also provides build scripts to create Amazon Elastic Container Service (Amazon ECS) and Amazon Elastic Kubernetes Service (Amazon EKS) AMIs.

After selecting an AMI, launch a dl1.24xlarge instance in either us-east-1 or us-west-2. To help identify in which availability zone(s) dl1.24xlarge is available, run the following command:

aws ec2 describe-instance-type-offerings \
--location-type availability-zone \
--filters Name=instance-type,Values=dl1.24xlarge \
--region us-west-2 \
--output table

Once launched, you can connect to the instance over SSH (with the correct security group attached).

Habana Collectives Communication Library (HCL/HCCL)

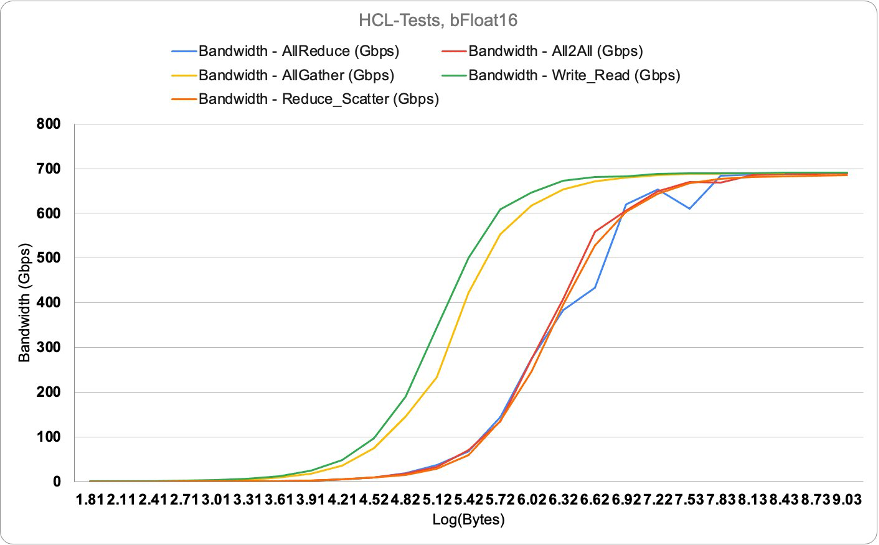
As part of the Habana SynapseAI SDK, Habana Gaudi’s use the HCCL library for handling the collectives between HPUs. Get more information on HCCL here. On DL1 through the HCL-tests, we can confirm close to 700 Gbps (689 Gbps) per card for the collectives tested as follows.

You can confirm these tests by cloning the github repo here.

Habana DL1 HCCL tests.

Amazon EKS Quick Start

Support for DL1 on Amazon EKS is available today with Amazon EKS versions > 1.19. The following is a quick start to get up and running quickly with DL1.

The following dependencies will be needed:

eksctl – You need version 0.70.0+ of eksctl.
kubectl – You use Kubernetes version 1.20 in this post.

Create EKS cluster:

eksctl create cluster --region us-east-1 --without-nodegroup \
--vpc-public-subnets subnet-037d8e430963c2d3e,subnet-0abe898359a7d43e9

Nodegroup configuration – save the following codeblock to a file called dl1-managed-ng.yaml. Replace the AMI ID in the code block with the AMI created earlier.

apiVersion: eksctl.io/v1alpha5
kind: ClusterConfig

metadata:
  name: fabulous-rainbow-1635807811
  region: us-west-2

vpc:
  id: vpc-34f1894c
  subnets:
    public:
      endpoint-one:
        id: subnet-4532e73d
      endpoint-two:
        id: subnet-8f8b7dc5

managedNodeGroups:
  - name: dl1-ng-1d
    instanceType: dl1.24xlarge
    volumeSize: 200
    instancePrefix: dl1-ng-1d-worker
    ami: ami-072c632cbbc2255b3
    iam:
      withAddonPolicies:
        imageBuilder: true
        autoScaler: true
        ebs: true
        fsx: true
        cloudWatch: true
    ssh:
      allow: true
      publicKeyName: amrragab-aws
    subnets:
    - endpoint-one
    minSize: 1
    desiredCapacity: 1
    maxSize: 4
    overrideBootstrapCommand: |
      #!/bin/bash
      /etc/eks/bootstrap.sh fabulous-rainbow-1635807811

Create the managed nodegroup with the following command:

eksctl create nodegroup -f dl1-managed-ng.yaml

Once the nodegroup has been completed, you must apply the habana-k8s-device-plugin

kubectl create -f https://vault.habana.ai/artifactory/docker-k8s-device-plugin/habana-k8s-device-plugin.yaml

Once completed, you should see the Gaudi devices as an allocatable resource in your EKS
cluster, presenting 8 Gaudi accelerators per DL1 node in the cluster.

Allocatable:

attachable-volumes-aws-ebs: 39
cpu:                        95690m
ephemeral-storage:          192188443124
habana.ai/gaudi:            8
hugepages-1Gi:              0
hugepages-2Mi:              30000Mi
memory:                     753055132Ki
pods:                       15

Example Distributed Machine Learning (ML) Workloads

The following tables are examples of Mixed Precision/FP32 training results comparing DL1 to the common GPU instances used for ML training.

Model: ResNet50
Framework: TensorFlow 2
Dataset: Imagenet2012
GitHub: https://github.com/HabanaAI/Model-
References/tree/master/TensorFlow/computer_vision/Resnets/resnet_keras

Instance Type Batch Size
Mixed Precision Training Throughput (images/sec)
8x Gaudi – 32 GB (dl1.24xlarge) 256 13036
8x A100 – 40 GB (p4d.24xlarge) 256 17921
8x V100 – 32 GB (p3dn.24xlarge) 256 9685
8x V100 – 16GB (p3.16xlarge) 256 8945

Model: Bert Large – Pretraining
Framework: Pytorch 1.9
Dataset: Wikipedia/BooksCorpus
GitHub: https://github.com/HabanaAI/Model-References/tree/master/PyTorch/nlp/bert

Instance Type Batch Size
@128 Sequence
Length
Mixed Precision Training Throughput (seq/sec)
8x Gaudi – 32 GB (dl1.24xlarge) 256 1318
8x A100 – 40 GB (p4d.24xlarge) 8192 2979
8x V100 – 32 GB (p3dn.24xlarge) 8192 1458
8x V100 – 16GB (p3.16xlarge) 8192 1013

You can find a more comprehensive list of ML models supported with performance data here. Support for containers with TensorFlow and Pytorch are also available. Furthermore, you can stay up-to-date with the operator support for TensorFlow and Pytorch.

CONCLUSION

We are excited to innovate on behalf of our customers and provide a diverse choice in ML accelerators with DL1 instances. The DL1 instances powered by Gaudi accelerators can provide up to 40% better price performance for training deep learning models as compared to current generation GPU-based EC2 instances. DL1 instances use the Habana SynapseAI SDK with framework support in Pytorch and TensorFlow. Additional future support for EFA with peer direct HPUs across nodes will also be supported. Now it’s time to go power up your ML workloads with Amazon EC2 DL1 instances.

15.3 Million Request-Per-Second DDoS Attack

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/05/15-3-million-request-per-second-ddos-attack.html

Cloudflare is reporting a large DDoS attack against an unnamed company “operating a crypto launchpad.”

While this isn’t the largest application-layer attack we’ve seen, it is the largest we’ve seen over HTTPS. HTTPS DDoS attacks are more expensive in terms of required computational resources because of the higher cost of establishing a secure TLS encrypted connection. Therefore it costs the attacker more to launch the attack, and for the victim to mitigate it. We’ve seen very large attacks in the past over (unencrypted) HTTP, but this attack stands out because of the resources it required at its scale.

The attack only lasted 15 seconds. No word on motive. Was this a test? Or was that 15-second delay critical for some other fraud?

News article.

Let’s Architect! Serverless architecture on AWS

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-serverless-architecture-on-aws/

Serverless architecture and computing allow you and your teams to focus on delivering business value in place of investing time tweaking the infrastructure characteristics. AWS is not only providing serverless computing as a service, but share that half of our new applications built by Amazon are using AWS Lambda, as noted by Andy Jassy in his 2020 re:Invent keynote.

In this post, we share insights into reimagining a serverless environment.

I Build Applications – Event-driven Architecture

Event-driven architecture is common in modern applications built with microservices, and it is the cornerstone for designing serverless workloads. It uses events to trigger and communicate between decoupled services.

With this video, you can learn how to start with a prototype then scale to mass adoption using decoupled systems that run when responding to, without needing to redesign. Danilo Poccia, Chief Evangelist at AWS, begins the session with the APIs, then gives an example on how to build an event-driven architecture using Amazon EventBridge. The session closes with how to understand what is happening in this exchange of events.

Event-driven communication with asynchronous invocation

Event-driven communication with asynchronous invocation

Building modern cloud applications? Think integration

This re:Invent 2021 session explains modern cloud applications based on serverless or microservices, and how connections between components define important characteristics, like scalability, availability, and coupling.

How your systems are interconnected describes your system’s essential properties, such as resiliency and changeability. Gregor Hohpe, AWS Enterprise Strategist, shares tips on what to consider when integrating different services, such as lifecycle, level of control over the systems you are integrating, and how integration becomes an integral part of your software delivery cycle. The goal is to use the same method to integrate at the same speed as software deployment.

Integration approaches with Gregor Hohpe

Integration approaches with Gregor Hohpe

Serverless architectural patterns and best practices

Serverless architectures require a mindset shift: existing patterns need to be revisited, and new patterns created using the new architecture style. For each pattern created by AWS, we provide operational, security, and reliability best practices and discuss potential challenges. We also demonstrate some patterns in reference architecture diagrams.

This session helps you identify services and applications to create serverless architectures and understand areas of potential savings, increased agility, and reliability in your organization. Heitor Lessa, Principal Solutions Architect at AWS, starts the session identifying the benefits of Lambda Power Tuning: he details setting up memory when there are hundreds of functions, then follows with best practices for the pattern created.

Best practices for serverless architecture

Best practices for serverless architecture

Best practices of advanced serverless developers

This session is an overview of architectural best practices, optimizations, and handy codes that can be used to build secure, scalable, and high-performance serverless applications.

Julian Wood, Senior Developer Advocate at AWS, provides the recommended practices for implementing serverless applications inside your company, such as Lambda, to transform and not transport, avoid monolithic services and functions, orchestrate workflow with step functions, choreograph events. Julian also touches on understanding different ways you can invoke Lambda functions and what you should be aware of with each invocation model.

Three types of AWS Lambda invocation models

Three types of AWS Lambda invocation models

Building next-gen applications with event-driven architectures

Maintaining data consistency across multiple services can be challenging. It can also be difficult to work with large amounts of data in different data stores and locations. Teams building microservices architectures often find that integration with other applications and external services can make their workloads more monolithic and tightly coupled.

In this session, you can learn how to use event-based architectures to decouple and decentralize application components. Coupling is not one-dimensional, and it’s a trade-off to balance and optimize over time. This video demonstrates patterns based on message queues and events: for each pattern you can learn the advantages, the disadvantages, and the options for building it on AWS.

Sam Dengler, Principal Solutions Architect at AWS, explains the mental models to apply while designing choreography and orchestration in a scenario with microservices. The strategy adopted by Taco Bell for identifying their bounded contexts is also detailed, as well as the architecture built on Lambda for running the business logic and on AWS Step Functions for orchestration.

Choreography and orchestration are two modes of interaction in a microservices architecture

Choreography and orchestration are two modes of interaction in a microservices architecture

See you next time!

Thanks for joining our discussion on serverless architecting! If you want to deep dive into the topic, read all about Serverless on AWS!

See you in a couple of weeks when we discuss architecting for resilience!

Looking for more architecture content? AWS Architecture Center provides reference architecture diagrams, vetted architecture solutions, Well-Architected best practices, patterns, icons, and more!

Other posts in this series

New Sophisticated Malware

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/05/new-sophisticated-malware.html

Mandiant is reporting on a new botnet.

The group, which security firm Mandiant is calling UNC3524, has spent the past 18 months burrowing into victims’ networks with unusual stealth. In cases where the group is ejected, it wastes no time reinfecting the victim environment and picking up where things left off. There are many keys to its stealth, including:

  • The use of a unique backdoor Mandiant calls Quietexit, which runs on load balancers, wireless access point controllers, and other types of IoT devices that don’t support antivirus or endpoint detection. This makes detection through traditional means difficult.
  • Customized versions of the backdoor that use file names and creation dates that are similar to legitimate files used on a specific infected device.
  • A live-off-the-land approach that favors common Windows programming interfaces and tools over custom code with the goal of leaving as light a footprint as possible.
  • An unusual way a second-stage backdoor connects to attacker-controlled infrastructure by, in essence, acting as a TLS-encrypted server that proxies data through the SOCKS protocol.

[…]

Unpacking this threat group is difficult. From outward appearances, their focus on corporate transactions suggests a financial interest. But UNC3524’s high-caliber tradecraft, proficiency with sophisticated IoT botnets, and ability to remain undetected for so long suggests something more.

From Mandiant:

Throughout their operations, the threat actor demonstrated sophisticated operational security that we see only a small number of threat actors demonstrate. The threat actor evaded detection by operating from devices in the victim environment’s blind spots, including servers running uncommon versions of Linux and network appliances running opaque OSes. These devices and appliances were running versions of operating systems that were unsupported by agent-based security tools, and often had an expected level of network traffic that allowed the attackers to blend in. The threat actor’s use of the QUIETEXIT tunneler allowed them to largely live off the land, without the need to bring in additional tools, further reducing the opportunity for detection. This allowed UNC3524 to remain undetected in victim environments for, in some cases, upwards of 18 months.

Using Pupil Reflection in Smartphone Camera Selfies

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/05/using-pupil-reflection-in-smartphone-camera-selfies.html

Researchers are using the reflection of the smartphone in the pupils of faces taken as selfies to infer information about how the phone is being used:

For now, the research is focusing on six different ways a user can hold a device like a smartphone: with both hands, just the left, or just the right in portrait mode, and the same options in horizontal mode.

It’s not a lot of information, but it’s a start. (It’ll be a while before we can reproduce these results from Blade Runner.)

Research paper.

Detecting data drift using Amazon SageMaker

Post Syndicated from Shibu Nair original https://aws.amazon.com/blogs/architecture/detecting-data-drift-using-amazon-sagemaker/

As companies continue to embrace the cloud and digital transformation, they use historical data in order to identify trends and insights. This data is foundational to power tools, such as data analytics and machine learning (ML), in order to achieve high quality results.

This is a time where major disruptions are not only lasting longer, but also happening more frequently, as discussed in a McKinsey article on risk and resilience. Any disruption—a pandemic, hurricane, or even blocked sailing routes—has a major impact on the patterns of data and can create anomalous behavior.

ML models are dependent on data insights to help plan and support production-ready applications. With any disruptions, data drift can occur. Data drift is unexpected and undocumented changes to data structure, semantics, and/or infrastructure. If there is data drift, the model performance will degrade and no longer provide an accurate guidance. To mitigate the effects of the disruption, data drift needs to be detected and the ML models quickly trained and adjusted accordingly.

This blog post explains how to approach changing data patterns in the age of disruption and how to mitigate its effects on ML models. We also discuss the steps of building a feedback loop to capture the request data in the production environment and create a data pipeline to store the data for profiling and baselining. Then, we explain how Amazon SageMaker Clarify can help detect data drift.

How to detect data drift

There are three stages to detecting data drift: data quality monitoring, model quality monitoring, and drift evaluation (see Figure 1).

Stages in detecting data drift

Figure 1. Stages in detecting data drift

Data quality monitoring establishes a profile of the input data during model training, and then continuously compares incoming data with the profile. Deviations in the data profile signal a drift in the input data.

You can also detect drift through model quality monitoring, which requires capturing actual values that can be compared with the predictions. For example, using weekly demand forecasting, you can compare the forecast quantities one week later with the actual demand. Some use cases can require extra steps to collect actual values. For example, product recommendations may require you to ask a selected group of consumers for their feedback to the recommendation.

SageMaker Clarify provides insights into your trained models, including importance of model features and any biases towards certain segments of the input data. Changes of these attributes between re-trained models also signal drift. Drift evaluation constitutes the monitoring data and mechanisms to detect changes and triggering consequent actions. With Amazon CloudWatch, you can define rules and thresholds that prompt drift notifications.

Figure 2 illustrates a basic architecture with the data sources for training and production (on the left) and the observed data concerning drift (on the right). You can use Amazon SageMaker Data Wrangler, a visual data preparation tool, to clean and normalize your input data for your ML task. You can store the features that you defined for your models in the Amazon SageMaker Feature Store, a fully managed, purpose-built repository to store, update, retrieve, and share ML features.

The white, rectangular boxes in the architecture diagram represent the tasks for detecting data and model drift. You can integrate those tasks into your ML workflow with Amazon SageMaker Pipelines.

Basic architecture on how data drift is detected using Amazon SageMaker

Figure 2. Basic architecture on how data drift is detected using Amazon SageMaker

The drift observation data can be captured in tabular format, such as comma-separated values or Parquet, on Amazon Simple Storage Service (S3) and analyzed with Amazon Athena and Amazon QuickSight.

How to build a feedback loop

The baselining task establishes a data profile from training data. It uses Amazon SageMaker Model Monitor and runs before training or re-training the model. The baseline profile is stored on Amazon S3 to be referenced by the data drift monitoring job.

The data drift monitoring task continuously profiles the input data, compares it with baseline, and the results are captured in CloudWatch. This tasks runs on its own computation resources using Deequ, which checks that the monitoring job does not slow down your ML inference flow and scales with the data. The frequency of running this task can be adjusted to control cost, which can depend on how rapidly you anticipate that the data may change.

The model quality monitoring task computes model performance metrics from actuals and predicted values. The origin of these data points depends on the use case. Demand forecasting use cases naturally capture actuals that can be used to validate past predictions. Other use cases can require extra steps to acquire ground-truth data.

CloudWatch is a monitoring and observability service with which you can define rules to act on deviation in model performance or data drift. With CloudWatch, you can setup alerts to users via e-mail or SMS, and it can automatically start the ML model re-training process.

Run the baseline task on your updated data set before re-training your model. Use the SageMaker model registry to catalog your ML models for production, manage model versions, and control the associate training metrics.

Gaining insight into data and models

SageMaker Clarify provides greater visibility into your training data and models, helping identify and limit bias and explain predictions. For example, the trained models may consider some features more strongly than others when generating predictions. Compare the feature importance and bias between model-provided versions for a better understanding of the changes.

Conclusion

As companies continue to use data analytics and ML to inform daily activity, data drift may become a more common occurrence. Recognizing that drift can have a direct impact on models and production-ready applications, it is important to architect to identify potential data drift and avoid downgrading the models and negatively impacting results. Failure to capture changes in data can result in loss of process confidence, downgraded model accuracy, or a bottom-line impact to the business.

Smithy Server and Client Generator for TypeScript (Developer Preview)

Post Syndicated from Adam Thomas original https://aws.amazon.com/blogs/devops/smithy-server-and-client-generator-for-typescript/

We’re excited to announce the Developer Preview of Smithy’s server and client generators for TypeScript. This enables developers to write concise, type-safe code in the same model-first manner that AWS has used to develop its services. Smithy is AWS’s open-source Interface Definition Language (IDL) for web services. AWS uses Smithy and its internal predecessor to model services, generate server scaffolding, and generate rich clients in multiple languages, such as the AWS SDKs.

If you’re unfamiliar with Smithy, check out the Smithy website and watch an introductory talk from Michael Dowling, Smithy’s Principal Engineer.

This post will demonstrate how you can write a simple Smithy model, write a service that implements the model, deploy it to AWS Lambda, and call it using a generated client.

What can the server generator do for me?

Using Smithy and its server generator unlocks model-first development. Model-first development puts your customers first. This forces you to define your interface first rather than let your API to become implicitly defined by your implementation choices.

Smithy’s server generator for TypeScript enables development at a higher level of abstraction. By making serialization, deserialization, and routing an implementation detail in generated code, service developers can focus on writing code against modeled types, rather than against raw HTTP requests. Your business logic and unit tests will be cleaner and more readable, and the way that your messages are represented on the wire is defined explicitly by a protocol, not implicitly by your JSON parser.

The server generator also lets you leverage TypeScript’s type safety. Not only is the business logic of your service written against strongly typed interfaces, but also you can reference your service’s types in your AWS Cloud Development Kit (AWS CDK) definition. This makes sure that your stack will fail at build time rather than deployment time if it’s out of sync with your model.

Finally, using Smithy for service generation lets you ship clients in Smithy’s growing portfolio of generated clients. We’re unveiling a developer preview of the client generator for TypeScript today as well, and we’ll continue to unveil more implementations in the future.

The architecture of a Smithy service

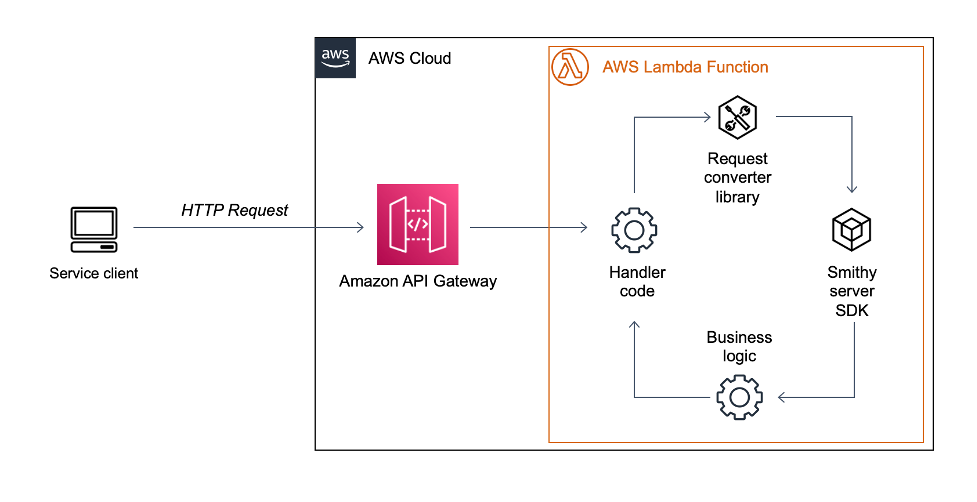
A Smithy service looks much like any other web service running on Lambda behind Amazon API Gateway. The difference lies in the code itself. Where a standard service might use a generic deserializer to parse an incoming request and bind it to an object, a Smithy service relies on code generation for deserialization, serialization, validation, and the object model itself. These functions are generated into a standalone library known as a Smithy server SDK. Using a server SDK with one of AWS’s prepackaged request converters, service developers can focus on their business logic, rather than the undifferentiated heavy lifting of parsing and generating HTTP requests and responses.

A data flow diagram for a Smithy service

Walkthrough

This post will walk you through the process of building and using a Smithy service, from modeling to deployment.

By the end, you should be able to:

  • Model a simple REST service in Smithy
  • Generate a Smithy server SDK for TypeScript
  • Implement a service in Lambda using the generated server SDK
  • Deploy the service to AWS using the AWS CDK
  • Generate a client SDK, and use it to call the deployed service

The complete example described in this post can be found here.

Prerequisites

For this walkthrough, you should have the following prerequisites:

Checking out the sample repository

Create a new repository from the template repository here.

To clone the application in your browser

  1. Open https://github.com/aws-samples/smithy-server-generator-typescript-sample in your browser
  2. Select “Use this template” in the top right-hand corner
  3. Fill out the form, and select “Create repository from template”
  4. Clone your new repository from GitHub by following the instructions in the “Code” dropdown

Exploring and setting up the sample application

The sample application is split into three separate submodules:

  • model – contains the Smithy model that defines the service
  • Server – contains the code generation setup, application logic, and CDK stack for the service
  • typescript-client – contains the code generation setup for a rich client generated in TypeScript

To bootstrap the sample application and run the initial build

  1. Open a terminal and navigate to the root of the sample application
  2. Run the following command:
    ./gradlew build && yarn install
  3. Wait until the build finishes successfully

Modeling a service using Smithy

In an IDE of your choice, open the file at model/src/main/smithy/main.smithy. This file defines the interface for the sample web service, a service that can echo strings back to the caller, as well as provide the string length.

The service definition forms the root of a Smithy model. It defines the operations that are available to clients, as well as common errors that are thrown by all of the operations in a service.


@sigv4(name: "execute-api")
@restJson1
service StringWizard {
    version: "2018-05-10",
    operations: [Echo, Length],
    errors: [ValidationException],
}

This service uses the @sigv4 trait to indicate that calls must be signed with AWS Signature V4. In the sample application, API Gateway’s Identity and Access Management (IAM) Authentication support provides this functionality.

@restJson1 indicates the protocol supported by this service. RestJson1 is Smithy’s built-in protocol for RESTful web services that use JSON for requests and responses.

This service advertises two operations: Echo and Length. Furthermore, it indicates that every operation on the service must be expected to throw ValidationException, if an invalid input is supplied.

Next, let’s look at the definition of the Length operation and its input type.

/// An operation that computes the length of a string
/// provided on the URI path
@readonly
@http(code: 200, method: "GET", uri: "/length/{string}",)
operation Length {
     input: LengthInput,
     output: LengthOutput,
     errors: [PalindromeException],
}

@input
structure LengthInput {
     @required
     @httpLabel
     string: String,
}

This operation uses the @http trait to model how requests are processed with restJson1, including the method (GET) and how the URI is formed (using a label to bind the string field from LengthInput to a path segment). HTTP binding with Smithy can be explored in depth at Smithy’s documentation page.

Note that this operation can also throw a PalindromeException, which we’ll explore in more detail when we check out the business logic.

Updating the Smithy model to add additional constraints to the input

Smithy constraint traits are used to enable additional validation for input types. Server SDKs automatically perform validation based on the Smithy constraints in the model. Let’s add a new constraint to the input for the Length operation. Moreover, let’s make sure that only alphanumeric characters can be passed in by the caller.

  1. Open model/src/main/smithy/main.smithy in an editor
  2. Add a @pattern constraint to the string member of Length input. It should look like this:
    structure LengthInput {
        @required
        @httpLabel
        @pattern(“^[a-zA-Z0-9]$”)
        string: String,
    }
  3. Open a terminal, and navigate to the root of the sample application
  4. Run the following command:
    yarn build
  5. Wait for the build to finish successfully

Using the Smithy Server Generator for TypeScript

The key component of a Smithy web service is its code generator, which translates the Smithy model into actual code. You’ve already run the code generator – it runs every time that you build the sample application.

The codegen directory inside of the server submodule is where the Smithy Server Generator for TypeScript is configured and run. The server generator uses Smithy Build to build, and it’s configured by smithy-build.json.

{
  "version" : "1.0",
  "outputDirectory" : "build/output",
  "projections" : {
      "ts-server" : {
         "plugins": {
           "typescript-ssdk-codegen" : {
              "package" : "@smithy-demo/string-wizard-service-ssdk",
              "packageVersion": "0.0.1"
           }
        }
      },
      "apigateway" : {
        "plugins" : {
          "openapi": {
             "service": "software.amazon.smithy.demo#StringWizard",
             "protocol": "aws.protocols#restJson1",
             "apiGatewayType" : "REST"
           }
         }
      }
   }
}

This smithy-build configures two projections. The ts-server projection generates the server SDK by invoking the typescript-ssdk-codegen plugin. The package and packageVersion arguments are used to generate an npm package that you can add as a dependency in your server code.

The OpenAPI projection configures Smithy’s OpenAPI converter to generate a file that can be imported into API Gateway to host this service. It uses Smithy’s ability to extend models via the imports keyword to extend the base model with an additional API Gateway configuration. The generated OpenAPI specification is used by the CDK stack, which we’ll explore later.

If you open package.json in the server submodule, then you’ll notice this line in the dependencies section:

"@smithy-demo/string-wizard-service-ssdk": "workspace:server/codegen/build/smithyprojections/server-codegen/ts-server/typescript-ssdk-codegen"

The key, @smithy-demo/string-wizard-service-ssdk, matches the package key in the smithy-build.json file. The value uses Yarn’s workspaces feature to set up a local dependency on the generated server SDK. This lets you use the server SDK as a standalone npm dependency without publishing it to a repository. Since we bundle the server application into a zip file before uploading it to Lambda, you can treat the server SDK as an implementation detail that isn’t published externally.

We won’t get into the details here, but you can see the specifics of how the code generator is invoked by looking at the regenerate:ssdk script in the server’s package.json, as well as the build.gradle file in the server’s codegen directory.

Implementing an operation using a server SDK

The server generator takes care of the undifferentiated heavy lifting of writing a Smithy service. However, there are still two tasks left for the service developer: writing the Lambda entrypoint, and implementing the operation’s business logic.

First, let’s look at the entrypoint for the Length operation. Open server/src/length_handler.ts in an editor. You should see the following content:

import { getLengthHandler } from "@smithy-demo/string-wizard-service-ssdk";
import { APIGatewayProxyHandler } from "aws-lambda";
import { LengthOperation } from "./length";
import { getApiGatewayHandler } from "./apigateway";
// This is the entry point for the Lambda Function that services the LengthOperation
export const lambdaHandler: APIGatewayProxyHandler = getApiGatewayHandler(getLengthHandler(LengthOperation));

If you’ve written a Lambda entry-point before, then exporting a function of type APIGatewayProxyHandler will be familiar to you. However, there are a few new pieces here. First, we have a function from the server SDK, called getLengthHandler, that takes a Smithy Operation type and returns a ServiceHandler. Operation is the interface that the server SDK uses to encapsulate business logic. The core task of implementing a Smithy service is to implement Operations. ServiceHandler is the interface that encapsulates the generated logic of a server SDK. It’s the black box that handles serialization, deserialization, error handling, validation, and routing.

The getApiGatewayHandler function simply invokes the request and response conversion logic, and then builds a custom context for the operation. We won’t go into their details here.

Next, let’s explore the operation implementation. Open server/src/length.ts in an editor. You should see the following content:

import { Operation } from "@aws-smithy/server-common";
import {
  LengthServerInput,
  LengthServerOutput,
  PalindromeException,
} from "@smithy-demo/string-wizard-service-ssdk";
import { HandlerContext } from "./apigateway";
import { reverse } from "./util";

// This is the implementation of business logic of the LengthOperation
export const LengthOperation: Operation<LengthServerInput, LengthServerOutput, HandlerContext> = async (
  input,
  context
) => {
  console.log(`Received Length operation from: ${context.user}`);

  if (input.string != undefined && input.string === reverse(input.string)) {
     throw new PalindromeException({ message: "Cannot handle palindrome" });
  }

  return {
     length: input.string?.length,
  };
};

Let’s look at this implementation piece-by-piece. First, the function type Operation<LengthServerInput, LengthServerOutput, HandlerContext> provides the type-safe interface for our business logic. LengthServerInput and LengthServerOutput are the code generated types that correspond to the input and output types for the Length operation in our Smithy model. If we use the wrong type arguments for the Operation, then it will fail type checks against the getLengthHandler function in the entry-point. If we try to access the incorrect properties on the input, then we’ll also see type checker failures. This is one of the core tenets of the Smithy Server Generator for TypeScript: writing a web service should be as strongly typed as writing anything else.

Next, let’s look at the section that validates that the input isn’t a palindrome:

if (input.string != undefined && input.string === reverse(input.string)) {
    throw new PalindromeException({ message: "Cannot handle palindrome" });
}

Although the server SDK can validate the input against Smithy’s constraint traits, there is no constraint trait for rejecting palindromes. Therefore, we must include this validation in our business logic. Our Smithy model includes a PalindromeException definition that includes a message member. This is generated as a standard subclass of Error with a constructor that takes in a message that your operation implementation can throw like any other error. This will be caught and properly rendered as a response by the server SDK.

Finally, there’s the return statement. Since the Smithy model defines LengthOutput as a structure containing an integer member called length, we return an object that has the same structural type here.

Note that this business logic doesn’t have to consider serialization, or the wire format of the request or response, let alone anything else related to HTTP or API Gateway. The unit tests in src/length/length.spec.ts reflect this. They’re the same standard unit tests as you would write against any other TypeScript class. The server SDK lets you write your business logic at a higher level of abstraction, thus simplifying your unit testing and letting your developers focus on their business logic rather than the messy details.

Deploying the sample application

The sample application utilizes the AWS CDK to deploy itself to your AWS account. Explore the CDK definition in server/lib/cdk-stack.ts. An in-depth exploration of the stack is out of the scope for this post, but it looks largely like any other AWS application that deploys TypeScript code to Lambda behind API Gateway.

The key difference is that the cdk stack can rely on a generated OpenAPI definition for the API Gateway resource. This makes sure that your deployed application always matches your Smithy model. Furthermore, it can use the server SDK’s generated types to make sure that every modeled operation has an implementation deployed to Lambda. This means that forgetting to wire up the implementation for a new operation becomes a compile-time failure, rather than a runtime one.

To deploy the sample application from the command line

    1. Open a terminal and navigate to the server directory of your sample application.
    2. Run the following command:
      yarn cdk deploy
    3. The cdk will display a list of security-sensitive resources that will be deployed to your account. These consist mostly of AWS Identity and Access Management (IAM) roles used by your Lambda functions for execution. Enter y to continue deploying the application to your account.
    4. When it has completed, the CDK will print your new application’s endpoint and the CloudFormation stack containing your application to the console. It will look something like the following:
      Outputs:
          StringWizardService.StringWizardApiEndpoint59072E9B
          = https://RANDOMSTRING.execute-api.us-west-2.amazonaws.com/prod/
      	
      Stack ARN:
          arn:aws:cloudformation:us-west-2:YOURACCOUNTID:stack/StringWizardService/SOME-UUID
    5. Log on to your AWS account in the AWS Management Console.
    6. Navigate to the Lambda console. You should see two new functions: one that starts with StringWizardService-EchoFunction, and one that starts with StringWizardService-EchoFunction. These are the implementations of your Smithy service’s operations.
    7. Navigate to the Amazon API Gateway console. You should see a new REST API named StringWizardAPI, with Resources POST /echo and GET /length/{string}, corresponding to your Smithy model.

    Calling the sample application with a generated client

    The last piece of the Smithy puzzle is the strongly-typed generated client generated by the Smithy Client Generator for TypeScript. It’s located in the typescript-client folder, which has a codegen folder that uses SmithyBuild to generate a client in much the same manner as the server.

    The sample application ships with a simple wrapper script for the length operation that uses the generated client to build a rudimentary CLI. Open the typescript-client/bin/length.ts file in your editor. The contents will look like the following:

    #!/usr/bin/env node
    
    import {LengthCommand, StringWizardClient} from "@smithy-demo/string-client";
    
    const client = new StringWizardClient({endpoint: process.argv[2]});
    
    client.send(new LengthCommand({
         string: process.argv[3]
    })).catch((err) => {
         console.log("Failed with error: " + err);
    process.exit(1);
    }).then((res) => {
         process.stderr.write(res.length?.toString() ?? "0");
    });

    If you’ve used the AWS SDK for JavaScript v3, this will look familiar. This is because it’s generated using the Smithy Client Generator for TypeScript!

    From the code, you can see that the CLI takes two positional arguments: the endpoint for the deployed application, and an input string. Let’s give it a spin.

    To call the deployed application using the generated client

    1. Open a terminal and navigate to the typescript-client directory.
    2. Run the following command to build the client:
      yarn build
    3. Using the endpoint output by the CDK in the Deploying the sample application section above, run the following command:
      yarn run str-length https://RANDOMSTRING.execute-api.us-west-2.amazonaws.com/prod/ foo 
    4. You should see an output of 3, the length of foo.
    5. Next, trigger anerror by calling your endpoint with a palindrome by running the following command:
      yarn run str-length https://RANDOMSTRING.execute-api.us-west-2.amazonaws.com/prod/ kayak
    6. You should see the following output:
      Failed with error: PalindromeException: Cannot handle palindrome

    Cleaning up

    To avoid incurring future charges, delete the resources.

    To delete the sample application using the CDK

    1. Open a terminal and navigate to the server directory.
    2. Run the following command:
      yarn cdk destroy StringWizardService
    3. Answer y to the prompt Are you sure you want to delete: StringWizardService (y/n)?
    4. Wait for the CDK to complete the deletion of your CloudFormation stack. You should see the following when it has completed:
      ✅ StringWizardService: destroyed

    Conclusion

    You have now used a Smithy model to define a service, explored how a generated server SDK can simplify your web service development, deployed the service to the AWS Cloud using the AWS CDK, and called the service using a strongly-typed generated client.

    If you aren’t familiar with Smithy, but you want to learn more, then don’t forget to check out the documentation or the introductory video.

    To learn more about the Smithy Server Generator for TypeScript, check out its documentation.

    If you have feature requests, bug reports, feedback of any kind, or would like to contribute, head over to the GitHub repository.

    Adam Thomas

    Adam Thomas is a Senior Software Development engineer on the Smithy team. He has been a web service developer at Amazon for over ten years. Outside of work, Adam is a passionate advocate for staying inside, playing video games, and reading fiction.

Friday Squid Blogging: Ten-Foot Long Squid Washed onto Japanese Shore — ALIVE

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/04/friday-squid-blogging-ten-foot-long-squid-washed-onto-japanese-shore-alive.html

This is rare:

An about 3-meter-long giant squid was found stranded on a beach here on April 20, in what local authorities said was a rare occurrence.

At around 10 a.m., a nearby resident spotted the squid at Ugu beach in Obama, Fukui Prefecture, on the Sea of Japan coast. According to the Obama Municipal Government, the squid was still alive when it was found. It is unusual for a giant squid to be washed ashore alive, officials said.

The deep-sea creature will be transported to Echizen Matsushima Aquarium in the prefectural city of Sakai.

Sadly, I do not expect the giant squid to survive, certainly not long enough for me to fly there and see it. But if any Japanese readers can supply more information, I would very much appreciate it.

BoingBoing post. Video.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

Video Conferencing Apps Sometimes Ignore the Mute Button

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/04/video-conferencing-apps-sometimes-ignore-the-mute-button.html

New research: “Are You Really Muted?: A Privacy Analysis of Mute Buttons in Video Conferencing Apps“:

Abstract: In the post-pandemic era, video conferencing apps (VCAs) have converted previously private spaces — bedrooms, living rooms, and kitchens — into semi-public extensions of the office. And for the most part, users have accepted these apps in their personal space, without much thought about the permission models that govern the use of their personal data during meetings. While access to a device’s video camera is carefully controlled, little has been done to ensure the same level of privacy for accessing the microphone. In this work, we ask the question: what happens to the microphone data when a user clicks the mute button in a VCA? We first conduct a user study to analyze users’ understanding of the permission model of the mute button. Then, using runtime binary analysis tools, we trace raw audio in many popular VCAs as it traverses the app from the audio driver to the network. We find fragmented policies for dealing with microphone data among VCAs — some continuously monitor the microphone input during mute, and others do so periodically. One app transmits statistics of the audio to its telemetry servers while the app is muted. Using network traffic that we intercept en route to the telemetry server, we implement a proof-of-concept background activity classifier and demonstrate the feasibility of inferring the ongoing background activity during a meeting — cooking, cleaning, typing, etc. We achieved 81.9% macro accuracy on identifying six common background activities using intercepted outgoing telemetry packets when a user is muted.

The paper will be presented at PETS this year.

News article.

Microsoft Issues Report of Russian Cyberattacks against Ukraine

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/04/microsoft-issues-report-of-russian-cyberattacks-against-ukraine.html

Microsoft has a comprehensive report on the dozens of cyberattacks — and even more espionage operations — Russia has conducted against Ukraine as part of this war:

At least six Russian Advanced Persistent Threat (APT) actors and other unattributed threats, have conducted destructive attacks, espionage operations, or both, while Russian military forces attack the country by land, air, and sea. It is unclear whether computer network operators and physical forces are just independently pursuing a common set of priorities or actively coordinating. However, collectively, the cyber and kinetic actions work to disrupt or degrade Ukrainian government and military functions and undermine the public’s trust in those same institutions.

[…]

Threat groups with known or suspected ties to the GRU have continuously developed and used destructive wiper malware or similarly destructive tools on targeted Ukrainian networks at a pace of two to three incidents a week since the eve of invasion. From February 23 to April 8, we saw evidence of nearly 40 discrete destructive attacks that permanently destroyed files in hundreds of systems across dozens of organizations in Ukraine.

Zero-Day Vulnerabilities Are on the Rise

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/04/zero-day-vulnerabilities-are-on-the-rise.html

Both Google and Mandiant are reporting a significant increase in the number of zero-day vulnerabilities reported in 2021.

Google:

2021 included the detection and disclosure of 58 in-the-wild 0-days, the most ever recorded since Project Zero began tracking in mid-2014. That’s more than double the previous maximum of 28 detected in 2015 and especially stark when you consider that there were only 25 detected in 2020. We’ve tracked publicly known in-the-wild 0-day exploits in this spreadsheet since mid-2014.

While we often talk about the number of 0-day exploits used in-the-wild, what we’re actually discussing is the number of 0-day exploits detected and disclosed as in-the-wild. And that leads into our first conclusion: we believe the large uptick in in-the-wild 0-days in 2021 is due to increased detection and disclosure of these 0-days, rather than simply increased usage of 0-day exploits.

Mandiant:

In 2021, Mandiant Threat Intelligence identified 80 zero-days exploited in the wild, which is more than double the previous record volume in 2019. State-sponsored groups continue to be the primary actors exploiting zero-day vulnerabilities, led by Chinese groups. The proportion of financially motivated actors­ — particularly ransomware groups — ­deploying zero-day exploits also grew significantly, and nearly 1 in 3 identified actors exploiting zero-days in 2021 was financially motivated. Threat actors exploited zero-days in Microsoft, Apple, and Google products most frequently, likely reflecting the popularity of these vendors. The vast increase in zero-day exploitation in 2021, as well as the diversification of actors using them, expands the risk portfolio for organizations in nearly every industry sector and geography, particularly those that rely on these popular systems.

News article.

How to control access to AWS resources based on AWS account, OU, or organization

Post Syndicated from Rishi Mehrotra original https://aws.amazon.com/blogs/security/how-to-control-access-to-aws-resources-based-on-aws-account-ou-or-organization/

AWS Identity and Access Management (IAM) recently launched new condition keys to make it simpler to control access to your resources along your Amazon Web Services (AWS) organizational boundaries. AWS recommends that you set up multiple accounts as your workloads grow, and you can use multiple AWS accounts to isolate workloads or applications that have specific security requirements. By using the new conditions, aws:ResourceOrgID, aws:ResourceOrgPaths, and aws:ResourceAccount, you can define access controls based on an AWS resource’s organization, organizational unit (OU), or account. These conditions make it simpler to require that your principals (users and roles) can only access resources inside a specific boundary within your organization. You can combine the new conditions with other IAM capabilities to restrict access to and from AWS accounts that are not part of your organization.

This post will help you get started using the new condition keys. We’ll show the details of the new condition keys and walk through a detailed example based on the following scenario. We’ll also provide references and links to help you learn more about how to establish access control perimeters around your AWS accounts.

Consider a common scenario where you would like to prevent principals in your AWS organization from adding objects to Amazon Simple Storage Service (Amazon S3) buckets that don’t belong to your organization. To accomplish this, you can configure an IAM policy to deny access to S3 actions unless aws:ResourceOrgID matches your unique AWS organization ID. Because the policy references your entire organization, rather than individual S3 resources, you have a convenient way to maintain this security posture across any number of resources you control. The new conditions give you the tools to create a security baseline for your IAM principals and help you prevent unintended access to resources in accounts that you don’t control. You can attach this policy to an IAM principal to apply this rule to a single user or role, or use service control policies (SCPs) in AWS Organizations to apply the rule broadly across your AWS accounts. IAM principals that are subject to this policy will only be able to perform S3 actions on buckets and objects within your organization, regardless of their other permissions granted through IAM policies or S3 bucket policies.

New condition key details

You can use the aws:ResourceOrgID, aws:ResourceOrgPaths, and aws:ResourceAccount condition keys in IAM policies to place controls on the resources that your principals can access. The following table explains the new condition keys and what values these keys can take.

Condition key Description Operator Single/multi value Value
aws:ResourceOrgID AWS organization ID of the resource being accessed All string operators Single value key Any AWS organization ID
aws:ResourceOrgPaths Organization path of the resource being accessed All string operators Multi-value key Organization paths of AWS organization IDs and organizational unit IDs
aws:ResourceAccount AWS account ID of the resource being accessed All string operators Single value key Any AWS account ID

Note: Of the three keys, only aws:ResourceOrgPaths is a multi-value condition key, while aws:ResourceAccount and aws:ResourceOrgID are single-value keys. For information on how to use multi-value keys, see Creating a condition with multiple keys or values in the IAM documentation.

Resource owner keys compared to principal owner keys

The new IAM condition keys complement the existing principal condition keys aws:PrincipalAccount, aws:PrincipalOrgPaths, and aws:PrincipalOrgID. The principal condition keys help you define which AWS accounts, organizational units (OUs), and organizations are allowed to access your resources. For more information on the principal conditions, see Use IAM to share your AWS resources with groups of AWS accounts in AWS Organizations on the AWS Security Blog.

Using the principal and resource keys together helps you establish permission guardrails around your AWS principals and resources, and makes it simpler to keep your data inside the organization boundaries you define as you continue to scale. For example, you can define identity-based policies that prevent your IAM principals from accessing resources outside your organization (by using the aws:ResourceOrgID condition). Next, you can define resource-based policies that prevent IAM principals outside your organization from accessing resources that are inside your organization boundary (by using the aws:PrincipalOrgID condition). The combination of both policies prevents any access to and from AWS accounts that are not part of your organization. In the next sections, we’ll walk through an example of how to configure the identity-based policy in your organization. For the resource-based policy, you can follow along with the example in An easier way to control access to AWS resources by using the AWS organization of IAM principals on the AWS Security blog.

Setup for the examples

In the following sections, we’ll show an example IAM policy for each of the new conditions. To follow along with Example 1, which uses aws:ResourceAccount, you’ll just need an AWS account.

To follow along with Examples 2 and 3 that use aws:ResourceOrgPaths and aws:ResourceOrgID respectively, you’ll need to have an organization in AWS Organizations and at least one OU created. This blog post assumes that you have some familiarity with the basic concepts in IAM and AWS Organizations. If you need help creating an organization or want to learn more about AWS Organizations, visit Getting Started with AWS Organizations in the AWS documentation.

Which IAM policy type should I use?

You can implement the following examples as identity-based policies, or in SCPs that are managed in AWS Organizations. If you want to establish a boundary for some of your IAM principals, we recommend that you use identity-based policies. If you want to establish a boundary for an entire AWS account or for your organization, we recommend that you use SCPs. Because SCPs apply to an entire AWS account, you should take care when you apply the following policies to your organization, and account for any exceptions to these rules that might be necessary for some AWS services to function properly.

Example 1: Restrict access to AWS resources within a specific AWS account

Let’s look at an example IAM policy that restricts access along the boundary of a single AWS account. For this example, say that you have an IAM principal in account 222222222222, and you want to prevent the principal from accessing S3 objects outside of this account. To create this effect, you could attach the following IAM policy.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": " DenyS3AccessOutsideMyBoundary",
      "Effect": "Deny",
      "Action": [
        "s3:*"
      ],
      "Resource": "*",
      "Condition": {
        "StringNotEquals": {
          "aws:ResourceAccount": [
            "222222222222"
          ]
        }
      }
    }
  ]
}

Note: This policy is not meant to replace your existing IAM access controls, because it does not grant any access. Instead, this policy can act as an additional guardrail for your other IAM permissions. You can use a policy like this to prevent your principals from access to any AWS accounts that you don’t know or control, regardless of the permissions granted through other IAM policies.

This policy uses a Deny effect to block access to S3 actions unless the S3 resource being accessed is in account 222222222222. This policy prevents S3 access to accounts outside of the boundary of a single AWS account. You can use a policy like this one to limit your IAM principals to access only the resources that are inside your trusted AWS accounts. To implement a policy like this example yourself, replace account ID 222222222222 in the policy with your own AWS account ID. For a policy you can apply to multiple accounts while still maintaining this restriction, you could alternatively replace the account ID with the aws:PrincipalAccount condition key, to require that the principal and resource must be in the same account (see example #3 in this post for more details how to accomplish this).

Organization setup: Welcome to AnyCompany

For the next two examples, we’ll use an example organization called AnyCompany that we created in AWS Organizations. You can create a similar organization to follow along directly with these examples, or adapt the sample policies to fit your own organization. Figure 1 shows the organization structure for AnyCompany.

Figure 1: Organization structure for AnyCompany

Figure 1: Organization structure for AnyCompany

Like all organizations, AnyCompany has an organization root. Under the root are three OUs: Media, Sports, and Governance. Under the Sports OU, there are three more OUs: Baseball, Basketball, and Football. AWS accounts in this organization are spread across all the OUs based on their business purpose. In total, there are six OUs in this organization.

Example 2: Restrict access to AWS resources within my organizational unit

Now that you’ve seen what the AnyCompany organization looks like, let’s walk through another example IAM policy that you can use to restrict access to a specific part of your organization. For this example, let’s say you want to restrict S3 object access within the following OUs in the AnyCompany organization:

  • Media
  • Sports
  • Baseball
  • Basketball
  • Football

To define a boundary around these OUs, you don’t need to list all of them in your IAM policy. Instead, you can use the organization structure to your advantage. The Baseball, Basketball, and Football OUs share a parent, the Sports OU. You can use the new aws:ResourceOrgPaths key to prevent access outside of the Media OU, the Sports OU, and any OUs under it. Here’s the IAM policy that achieves this effect.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": " DenyS3AccessOutsideMyBoundary",
      "Effect": "Deny",
      "Action": [
        "s3:*"
      ],
      "Resource": "*",
      "Condition": {
        "ForAllValues:StringNotLike": {
          "aws:ResourceOrgPaths": [
            "o-acorg/r-acroot/ou-acroot-mediaou/",
            "o-acorg/r-acroot/ou-acroot-sportsou/*"
          ] 
        }
      }
    }
  ]
}

Note: Like the earlier example, this policy does not grant any access. Instead, this policy provides a backstop for your other IAM permissions, preventing your principals from accessing S3 objects outside an OU-defined boundary. If you want to require that your IAM principals consistently follow this rule, we recommend that you apply this policy as an SCP. In this example, we attached this policy to the root of our organization, applying it to all principals across all accounts in the AnyCompany organization.

The policy denies access to S3 actions unless the S3 resource being accessed is in a specific set of OUs in the AnyCompany organization. This policy is identical to Example 1, except for the condition block: The condition requires that aws:ResourceOrgPaths contains any of the listed OU paths. Because aws:ResourceOrgPaths is a multi-value condition, the policy uses the ForAllValues:StringNotLike operator to compare the values of aws:ResourceOrgPaths to the list of OUs in the policy.

The first OU path in the list is for the Media OU. The second OU path is the Sports OU, but it also adds the wildcard character * to the end of the path. The wildcard * matches any combination of characters, and so this condition matches both the Sports OU and any other OU further down its path. Using wildcards in the OU path allows you to implicitly reference other OUs inside the Sports OU, without having to list them explicitly in the policy. For more information about wildcards, refer to Using wildcards in resource ARNs in the IAM documentation.

Example 3: Restrict access to AWS resources within my organization

Finally, we’ll look at a very simple example of a boundary that is defined at the level of an entire organization. This is the same use case as the preceding two examples (restrict access to S3 object access), but scoped to an organization instead of an account or collection of OUs.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "DenyS3AccessOutsideMyBoundary",
      "Effect": "Deny",
      "Action": [
        "s3:*"
      ],
      "Resource": "arn:aws:s3:::*/*",
      "Condition": {
        "StringNotEquals": {
          "aws:ResourceOrgID": "${aws:PrincipalOrgID}"
        }
      }
    }
  ]
}

Note: Like the earlier examples, this policy does not grant any access. Instead, this policy provides a backstop for your other IAM permissions, preventing your principals from accessing S3 objects outside your organization regardless of their other access permissions. If you want to require that your IAM principals consistently follow this rule, we recommend that you apply this policy as an SCP. As in the previous example, we attached this policy to the root of our organization, applying it to all accounts in the AnyCompany organization.

The policy denies access to S3 actions unless the S3 resource being accessed is in the same organization as the IAM principal that is accessing it. This policy is identical to Example 1, except for the condition block: The condition requires that aws:ResourceOrgID and aws:PrincipalOrgID must be equal to each other. With this requirement, the principal making the request and the resource being accessed must be in the same organization. This policy also applies to S3 resources that are created after the policy is put into effect, so it is simple to maintain the same security posture across all your resources.

For more information about aws:PrincipalOrgID, refer to AWS global condition context keys in the IAM documentation.

Learn more

In this post, we explored the new conditions, and walked through a few examples to show you how to restrict access to S3 objects across the boundary of an account, OU, or organization. These tools work for more than just S3, though: You can use the new conditions to help you protect a wide variety of AWS services and actions. Here are a few links that you may want to look at:

If you have any questions, comments, or concerns, contact AWS Support or start a new thread on the AWS Identity and Access Management forum. Thanks for reading about this new feature. If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security news? Follow us on Twitter.

Rishi Mehrotra

Rishi Mehrotra

Rishi is a Product Manager in AWS IAM. He enjoys working with customers and influencing products decisions. Prior to Amazon, Rishi worked for enterprise IT customers after receiving engineering degree in computer science. He recently pursued MBA from The University of Chicago Booth School of Business. Outside of work, Rishi enjoys biking, reading, and playing with his kids.

Author

Michael Switzer

Mike is the product manager for the Identity and Access Management service at AWS. He enjoys working directly with customers to identify solutions to their challenges, and using data-driven decision making to drive his work. Outside of work, Mike is an avid cyclist and outdoorsperson. He holds a master’s degree in computational mathematics from the University of Washington.

Registering SMS Sender IDs in Singapore

Post Syndicated from Brent Meyer original https://aws.amazon.com/blogs/messaging-and-targeting/registering-sms-sender-ids-in-singapore/

A few weeks ago, we published a blog post about the process of registering alphanumeric Sender IDs. Today, we’re announcing support for registering Sender IDs in Singapore.

About Sender ID registration in Singapore

Singapore’s Infocomm Media Development Authority (IMDA) has created a Sender ID registry to protect consumers from fraudulent and malicious SMS messages. This registry is called the Singapore SMS Sender ID Registry (SSIR).

The government of Singapore encourages all government agencies and financial institutions to register with SSIR. Organizations and businesses outside of these industries can also register with SSIR.

Currently, there is no requirement to register your Sender ID. However, when you register with the SSIR, your Sender ID becomes a “Protected Sender ID.” Protected Sender IDs help to protect you and your customers by preventing other senders from using your Sender ID.

Note that in order to complete this registration process, your business or organization must have a Unique Entity Number (UEN). Businesses and other organizations receive a UEN when they register with Singapore’s Accounting and Corporate Regulatory Authority.

Registering your Sender ID

The first step in the registration process is to create a Protected Sender ID through the Singapore Network Information Centre (SGNIC). To initiate the registration process, send an email to [email protected]. In your message, include the name of your business, the Sender IDs that you want to register, and a description of your use case. SGNIC may contact you for additional information.

After you register with SGNIC, open a ticket in the AWS Support Center. You can find the procedure for opening a case in the Amazon Pinpoint User Guide. The AWS Support team will respond to your case within 24 hours. Their response includes a template for a letter that shows your intent to register a Sender ID.

The next step is to modify the contents of this letter. The regulatory groups in Singapore require a copy of this letter in order to allow AWS to send messages using your Sender ID. Begin by placing the contents of the letter on your company’s letterhead. Next, modify the fields that are highlighted in yellow. These fields include the following:

  • <Place>: The address of your company or organization.
  • <Brand Owner Company Name>: The name of your company or organization.
  • <Number>: Your Unique Entity Number.
  • <Signature>, <Name>, <Title>: The personal signature, name, and job title of the person who is submitting the request on behalf of your company or organization.
  • <ExampleSenderId1>, <ExampleSenderId2>: The Sender IDs that you intend to register with SGNIC. You can add or remove lines here depending on how many Sender IDs you plan to register.

Once you finish modifying the letter, submit it by attaching it to your existing case in the AWS Support Center.

What happens next?

IMDA regularly sends us lists of new Sender ID registrations. When we receive confirmation that your Sender ID has been registered, we update your account to allow it to send SMS messages through your Sender ID. We will also comment on your Support case to indicate that the process is complete.

Wrapping up

We continue to monitor changes to Sender ID registration requirements around the world. We’re working closely with carriers and organizations around the world to make the registration processes as straightforward as possible for our customers. Check in on this blog regularly to learn more about future regulatory changes.

For more information about registering Sender IDs in Singapore, see Special requirements for Singapore in the Amazon Pinpoint User Guide.

SMS Phishing Attacks are on the Rise

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/04/sms-phishing-attacks-are-on-the-rise.html

SMS phishing attacks — annoyingly called “smishing” — are becoming more common.

I know that I have been receiving a lot of phishing SMS messages over the past few months. I am not getting the “Fedex package delivered” messages the article talks about. Mine are usually of the form: “Thank you for paying your bill, here’s a free gift for you.”

Friday Squid Blogging: Squid Skin–Inspired Insulating Material

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/04/friday-squid-blogging-squid-skin-inspired-insulating-material.html

Interesting:

Drawing inspiration from cephalopod skin, engineers at the University of California, Irvine invented an adaptive composite material that can insulate beverage cups, restaurant to-go bags, parcel boxes and even shipping containers.

[…]

“The metal islands in our composite material are next to one another when the material is relaxed and become separated when the material is stretched, allowing for control of the reflection and transmission of infrared light or heat dissipation,” said Gorodetsky. “The mechanism is analogous to chromatophore expansion and contraction in a squid’s skin, which alters the reflection and transmission of visible light.”

Chromatophore size changes help squids communicate and camouflage their bodies to evade predators and hide from prey. Gorodetsky said by mimicking this approach, his team has enabled “tunable thermoregulation” in their material, which can lead to improved energy efficiency and protect sensitive fingers from hot surfaces.

Research paper.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.