Post Syndicated from Crosstalk Solutions original https://www.youtube.com/watch?v=S2vE6xANFvk
Woodstock: Financial Fiasco to Success
Post Syndicated from Geographics original https://www.youtube.com/watch?v=-DaD8eLmzAQ
Microsoft Azure Cobalt 100 128 Core Arm Neoverse N2 CPU Launched
Post Syndicated from John Lee original https://www.servethehome.com/microsoft-azure-cobalt-100-128-core-arm-neoverse-n2-cpu-launched/
The Microsoft Azure Cobalt 100 is a new 128 core Arm Neoverse N2 processor designed for Microsoft’s cloud-native compute
The post Microsoft Azure Cobalt 100 128 Core Arm Neoverse N2 CPU Launched appeared first on ServeTheHome.
Decentralize LF-tag management with AWS Lake Formation
Post Syndicated from Ramkumar Nottath original https://aws.amazon.com/blogs/big-data/decentralize-lf-tag-management-with-aws-lake-formation/
In today’s data-driven world, organizations face unprecedented challenges in managing and extracting valuable insights from their ever-expanding data ecosystems. As the number of data assets and users grow, the traditional approaches to data management and governance are no longer sufficient. Customers are now building more advanced architectures to decentralize permissions management to allow for individual groups of users to build and manage their own data products, without being slowed down by a central governance team. One of the core features of AWS Lake Formation is the delegation of permissions on a subset of resources such as databases, tables, and columns in AWS Glue Data Catalog to data stewards, empowering them make decisions regarding who should get access to their resources and helping you decentralize the permissions management of your data lakes. Lake Formation has added a new capability that further allows data stewards to create and manage their own Lake Formation tags (LF-tags). Lake Formation tag-based access control (LF-TBAC) is an authorization strategy that defines permissions based on attributes. In Lake Formation, these attributes are called LF-Tags. LF-TBAC is the recommended method to use to grant Lake Formation permissions when there is a large number of Data Catalog resources. LF-TBAC is more scalable than the named resource method and requires less permission management overhead.
In this post, we go through the process of delegating the LF-tag creation, management, and granting of permissions to a data steward.
Lake Formation serves as the foundation for these advanced architectures by simplifying security management and governance for users at scale across AWS analytics. Lake Formation is designed to address these challenges by providing secure sharing between AWS accounts and tag-based access control to be able scale permissions. By assigning tags to data assets based on their characteristics and properties, organizations can implement access control policies tailored to specific data attributes. This ensures that only authorized individuals or teams can access and work with the data relevant to their domain. For example, it allows customers to tag data assets as “Confidential” and grant access to that LF-Tag to only those users who should have access to confidential data. Tag-based access control not only enhances data security and privacy, but also promotes efficient collaboration and knowledge sharing.
The need for producer autonomy and decentralized tag creation and delegation in data governance is paramount, regardless of the architecture chosen, whether it be a single account, hub and spoke, or data mesh with central governance. Relying solely on centralized tag creation and governance can create bottlenecks, hinder agility, and stifle innovation. By granting producers and data stewards the autonomy to create and manage tags relevant to their specific domains, organizations can foster a sense of ownership and accountability among producer teams. This decentralized approach allows you to adapt and respond quickly to changing requirements. This methodology helps organizations strike a balance between central governance and producer ownership, leading to improved governance, enhanced data quality, and data democratization.
Lake Formation announced the tag delegation feature to address this. With this feature, a Lake Formation admin can now provide permission to AWS Identity and Access Management (IAM) users and roles to create tags, associate them, and manage the tag expressions.
Solution overview
In this post, we examine an example organization that has a central data lake that is being used by multiple groups. We have two personas: the Lake Formation administrator LFAdmin, who manages the data lake and onboards different groups, and the data steward LFDataSteward-Sales, who owns and manages resources for the Sales group within the organization. The goal is to grant permission to the data steward to be able to use LF-Tags to perform permission grants for the resources that they own. In addition, the organization has a set of common LF-Tags called Confidentiality and Department, which the data steward will be able to use.
The following diagram illustrates the workflow to implement the solution.

The following are the high-level steps:
- Grant permissions to create LF-Tags to a user who is not a Lake Formation administrator (the
LFDataSteward-SalesIAM role). - Grant permissions to associate an organization’s common LF-Tags to the
LFDataSteward-Salesrole. - Create new LF-Tags using the
LFDataSteward-Salesrole. - Associate the new and common LF-Tags to resources using the
LFDataSteward-Salesrole. - Grant permissions to other users using the
LFDataSteward-Salesrole.
Prerequisites
For this walkthrough, you should have the following:
- An AWS account.
- Knowledge of using Lake Formation and enabling Lake Formation to manage permissions to a set of tables.
- An IAM role that is a Lake Formation administrator. For this post, we name ours
LFAdmin. - Two LF-Tags created by the
LFAdmin:- Key Confidentiality with values
PIIandPublic. - Key Department with values
SalesandMarketing.
- Key Confidentiality with values
- An IAM role that is a data steward within an organization. For this post, we name ours
LFDataSteward-Sales. - The data steward should have ‘Super’ access to at least one database. In this post, the data steward has access to three databases:
sales-ml-data,sales-processed-data, andsales-raw-data. - An IAM role to serve as a user that the data steward will grant permissions to using LF-Tags. For this post, we name ours
LFAnalysts-MLScientist.
Grant permission to the data steward to be able to create LF-Tags
Complete the following steps to grant LFDataSteward-Sales the ability to create LF-Tags:
- As the
LFAdminrole, open the Lake Formation console. - In the navigation pane, choose LF-Tags and permissions under Permissions.
Under LF-Tags, because you are logged in as LFAdmin, you can see all the tags that have been created within the account. You can see the Confidentiality LF-Tag as well as the Department LF-Tag and the possible values for each tag.

- On the LF-Tag creators tab, choose Add LF-Tag creators.

- For IAM users and roles, enter the
LFDataSteward-SalesIAM role. - For Permission, select Create LF-Tag.
- If you want this data steward to be able to grant Create LF-Tag permissions to other users, select Create LF-Tag under Grantable permission.
- Choose Add.

The LFDataSteward-Sales IAM role now has permissions to create their own LF-Tags.

Grant permission to the data steward to use common LF-Tags
We now want to give permission to the data steward to tag using the Confidentiality and Department tags. Complete the following steps:
- As the
LFAdminrole, open the Lake Formation console. - In the navigation pane, choose LF-Tags and permissions under Permissions.
- On the LF-Tag permissions tab, choose Grant permissions.

- Select LF-Tag key-value permission for Permission type.
The LF-Tag permission option grants the ability to modify or drop an LF-Tag, which doesn’t apply in this use case.

- Select IAM users and roles and enter the
LFDataSteward-SalesIAM role.

- Provide the
ConfidentialityLF-Tag and all its values, and theDepartmentLF-Tag with only theSalesvalue. - Select Describe, Associate, and Grant with LF-Tag expression under Permissions.
- Choose Grant permissions.

This gave the LFDataSteward-Sales role the ability to tag resources using the Confidentiality tag and all its values as well as the Department tag with only the Sales value.
Create new LF-Tags using the data steward role
This step demonstrates how the LFDataSteward-Sales role can now create their own LF-Tags.
- As the
LFDataSteward-Salesrole, open the Lake Formation console. - In the navigation pane, choose LF-Tags and permissions under Permissions.
The LF-Tags section only shows the Confidentiality tag and Department tag with only the Sales value. As the data steward, we want to create our own LF-Tags to make permissioning easier.
- Choose Add LF-Tag.

- For Key, enter
Sales-Subgroups. - For Values¸ enter
DataScientists,DataEngineers, andMachineLearningEngineers. - Choose Add LF-Tag.

As the LF-Tag creator, the data steward has full permissions on the tags that they created. You will be able to see all the tags that the data steward has access to.

Associate LF-Tags to resources as the data steward
We now associate resources to the LF-Tags that we just created so that Machine Learning Engineers can have access to the sales-ml-data resource.
- As the
LFDataSteward-Salesrole, open the Lake Formation console. - In the navigation pane, choose Databases.
- Select
sales-ml-dataand on the Actions menu, choose Edit LF-Tags.

- Add the following LF-Tags and values:
- Key
Sales-Subgroupswith valueMachineLearningEngineers. - Key
Departmentwith valueanalytics. - Key
Confidentialitywith valuePublic.
- Key
- Choose Save.

Grant permissions using LF-Tags as the data steward
To grant permissions using LF-Tags, complete the following steps:
- As the
LFDataSteward-Salesrole, open the Lake Formation console. - In the navigation pane, choose Data lake permissions under Permissions.
- Choose Grant.
- Select IAM users and roles and enter the IAM principal to grant permission to (for this example, the
Sales-MLScientistrole).

- In the LF-Tags or catalog resources section, select Resources matched by LF-Tags.
- Enter the following tag expressions:
- For the
DepartmentLF-Tag, set theSalesvalue. - For the
Sales-SubgroupsLF-Tag, set theMachineLearningEngineersvalue. - For the
ConfidentialityLF-Tag, set thePublicvalue.
- For the

Because this is a machine learning (ML) and data science user, we want to give full permissions so that they can manage databases and create tables.
- For Database permissions, select Super, and for Table permissions, select Super.

- Choose Grant.
We now see the permissions granted to the LF-Tag expression.

Verify permissions granted to the user
To verify permissions using Amazon Athena, navigate to the Athena console as the Sales-MLScientist role. We can observe that the Sales-MLScientist role now has access to the sales-ml-data database and all the tables. In this case, there is only one table, sales-report.

Clean up
To clean up your resources, delete the following:
- IAM roles that you may have created for the purposes of this post
- Any LF-Tags that you created
Conclusion
In this post, we discussed the benefits of decentralized tag management and how the new Lake Formation feature helps implement this. By granting permission to producer teams’ data stewards to manage tags, organizations empower them to use their domain knowledge and capture the nuances of their data effectively. Furthermore, granting permission to data stewards enables them to take ownership of the tagging process, ensuring accuracy and relevance.
The post illustrated the various steps involved in decentralized Lake Formation tag management, such as granting permission to data stewards to create LF-Tags and use common LF-Tags. We also demonstrated how the data steward can create their own LF-Tags, associate the tags to resources, and grant permissions using tags.
We encourage you to explore the new decentralized Lake Formation tag management feature. For more details, see Lake Formation tag-based access control.
About the Authors
 Ramkumar Nottath is a Principal Solutions Architect at AWS focusing on Analytics services. He enjoys working with various customers to help them build scalable, reliable big data and analytics solutions. His interests extend to various technologies such as analytics, data warehousing, streaming, data governance, and machine learning. He loves spending time with his family and friends.
 Mert Hocanin is a Principal Big Data Architect at AWS within the AWS Lake Formation Product team. He has been with Amazon for over 10 years, and enjoys helping customers build their data lakes with a focus on governance on a wide variety of services. When he isn’t helping customers build data lakes, he spends his time with his family and traveling.
Use generative AI with Amazon EMR, Amazon Bedrock, and English SDK for Apache Spark to unlock insights
Post Syndicated from Saurabh Bhutyani original https://aws.amazon.com/blogs/big-data/use-generative-ai-with-amazon-emr-amazon-bedrock-and-english-sdk-for-apache-spark-to-unlock-insights/
In this era of big data, organizations worldwide are constantly searching for innovative ways to extract value and insights from their vast datasets. Apache Spark offers the scalability and speed needed to process large amounts of data efficiently.
Amazon EMR is the industry-leading cloud big data solution for petabyte-scale data processing, interactive analytics, and machine learning (ML) using open source frameworks such as Apache Spark, Apache Hive, and Presto. Amazon EMR is the best place to run Apache Spark. You can quickly and effortlessly create managed Spark clusters from the AWS Management Console, AWS Command Line Interface (AWS CLI), or Amazon EMR API. You can also use additional Amazon EMR features, including fast Amazon Simple Storage Service (Amazon S3) connectivity using the Amazon EMR File System (EMRFS), integration with the Amazon EC2 Spot market and the AWS Glue Data Catalog, and EMR Managed Scaling to add or remove instances from your cluster. Amazon EMR Studio is an integrated development environment (IDE) that makes it straightforward for data scientists and data engineers to develop, visualize, and debug data engineering and data science applications written in R, Python, Scala, and PySpark. EMR Studio provides fully managed Jupyter notebooks, and tools like Spark UI and YARN Timeline Service to simplify debugging.
To unlock the potential hidden within the data troves, it’s essential to go beyond traditional analytics. Enter generative AI, a cutting-edge technology that combines ML with creativity to generate human-like text, art, and even code. Amazon Bedrock is the most straightforward way to build and scale generative AI applications with foundation models (FMs). Amazon Bedrock is a fully managed service that makes FMs from Amazon and leading AI companies available through an API, so you can quickly experiment with a variety of FMs in the playground, and use a single API for inference regardless of the models you choose, giving you the flexibility to use FMs from different providers and keep up to date with the latest model versions with minimal code changes.
In this post, we explore how you can supercharge your data analytics with generative AI using Amazon EMR, Amazon Bedrock, and the pyspark-ai library. The pyspark-ai library is an English SDK for Apache Spark. It takes instructions in English language and compiles them into PySpark objects like DataFrames. This makes it straightforward to work with Spark, allowing you to focus on extracting value from your data.
Solution overview
The following diagram illustrates the architecture for using generative AI with Amazon EMR and Amazon Bedrock.
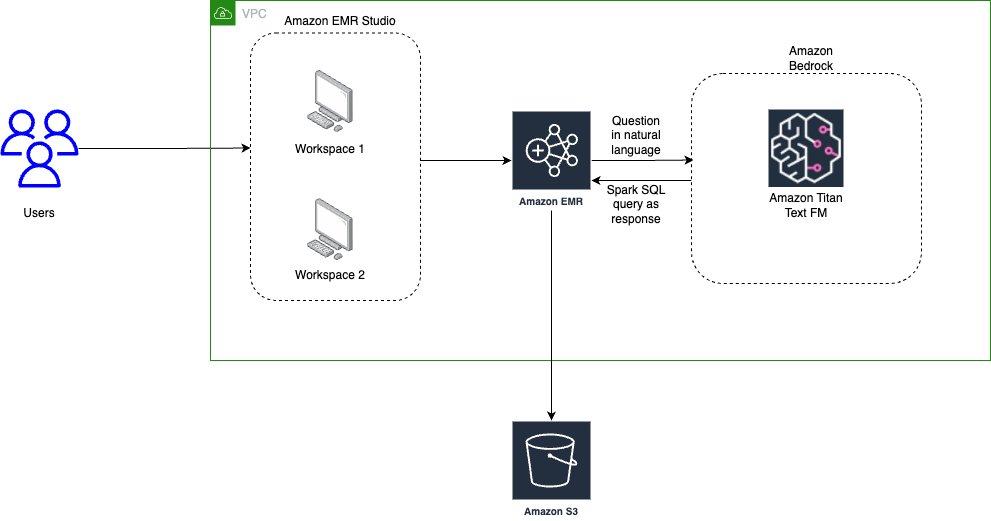
EMR Studio is a web-based IDE for fully managed Jupyter notebooks that run on EMR clusters. We interact with EMR Studio Workspaces connected to a running EMR cluster and run the notebook provided as part of this post. We use the New York City Taxi data to garner insights into various taxi rides taken by users. We ask the questions in natural language on top of the data loaded in Spark DataFrame. The pyspark-ai library then uses the Amazon Titan Text FM from Amazon Bedrock to create a SQL query based on the natural language question. The pyspark-ai library takes the SQL query, runs it using Spark SQL, and provides results back to the user.
In this solution, you can create and configure the required resources in your AWS account with an AWS CloudFormation template. The template creates the AWS Glue database and tables, S3 bucket, VPC, and other AWS Identity and Access Management (IAM) resources that are used in the solution.
The template is designed to demonstrate how to use EMR Studio with the pyspark-ai package and Amazon Bedrock, and is not intended for production use without modification. Additionally, the template uses the us-east-1 Region and may not work in other Regions without modification. The template creates resources that incur costs while they are in use. Follow the cleanup steps at the end of this post to delete the resources and avoid unnecessary charges.
Prerequisites
Before you launch the CloudFormation stack, ensure you have the following:
- An AWS account that provides access to AWS services
- An IAM user with an access key and secret key to configure the AWS CLI, and permissions to create an IAM role, IAM policies, and stacks in AWS CloudFormation
- The Titan Text G1 – Express model is currently in preview, so you need to have preview access to use it as part of this post
Create resources with AWS CloudFormation
The CloudFormation creates the following AWS resources:
- A VPC stack with private and public subnets to use with EMR Studio, route tables, and NAT gateway.
- An EMR cluster with Python 3.9 installed. We are using a bootstrap action to install Python 3.9 and other relevant packages like pyspark-ai and Amazon Bedrock dependencies. (For more information, refer to the bootstrap script.)
- An S3 bucket for the EMR Studio Workspace and notebook storage.
- IAM roles and policies for EMR Studio setup, Amazon Bedrock access, and running notebooks
To get started, complete the following steps:
- Choose Launch Stack:

- Select I acknowledge that this template may create IAM resources.

The CloudFormation stack takes approximately 20–30 minutes to complete. You can monitor its progress on the AWS CloudFormation console. When its status reads CREATE_COMPLETE, your AWS account will have the resources necessary to implement this solution.
Create EMR Studio
Now you can create an EMR Studio and Workspace to work with the notebook code. Complete the following steps:
- On the EMR Studio console, choose Create Studio.
- Enter the Studio Name as
GenAI-EMR-Studioand provide a description. - In the Networking and security section, specify the following:
- For VPC, choose the VPC you created as part of the CloudFormation stack that you deployed. Get the VPC ID using the CloudFormation outputs for the VPCID key.
- For Subnets, choose all four subnets.
- For Security and access, select Custom security group.
- For Cluster/endpoint security group, choose
EMRSparkAI-Cluster-Endpoint-SG. - For Workspace security group, choose
EMRSparkAI-Workspace-SG.
- In the Studio service role section, specify the following:
- For Authentication, select AWS Identity and Access Management (IAM).
- For AWS IAM service role, choose
EMRSparkAI-StudioServiceRole.
- In the Workspace storage section, browse and choose the S3 bucket for storage starting with
emr-sparkai-<account-id>. - Choose Create Studio.

- When the EMR Studio is created, choose the link under Studio Access URL to access the Studio.

- When you’re in the Studio, choose Create workspace.
- Add
emr-genaias the name for the Workspace and choose Create workspace. - When the Workspace is created, choose its name to launch the Workspace (make sure you’ve disabled any pop-up blockers).


Big data analytics using Apache Spark with Amazon EMR and generative AI
Now that we have completed the required setup, we can start performing big data analytics using Apache Spark with Amazon EMR and generative AI.
As a first step, we load a notebook that has the required code and examples to work with the use case. We use NY Taxi dataset, which contains details about taxi rides.
- Download the notebook file NYTaxi.ipynb and upload it to your Workspace by choosing the upload icon.

- After the notebook is imported, open the notebook and choose
PySparkas the kernel.

PySpark AI by default uses OpenAI’s ChatGPT4.0 as the LLM model, but you can also plug in models from Amazon Bedrock, Amazon SageMaker JumpStart, and other third-party models. For this post, we show how to integrate the Amazon Bedrock Titan model for SQL query generation and run it with Apache Spark in Amazon EMR.
- To get started with the notebook, you need to associate the Workspace to a compute layer. To do so, choose the Compute icon in the navigation pane and choose the EMR cluster created by the CloudFormation stack.

- Configure the Python parameters to use the updated Python 3.9 package with Amazon EMR:
- Import the necessary libraries:
- After the libraries are imported, you can define the LLM model from Amazon Bedrock. In this case, we use amazon.titan-text-express-v1. You need to enter the Region and Amazon Bedrock endpoint URL based on your preview access for the Titan Text G1 – Express model.
- Connect Spark AI to the Amazon Bedrock LLM model for SQL query generation based on questions in natural language:

Here, we have initialized Spark AI with verbose=False; you can also set verbose=True to see more details.
Now you can read the NYC Taxi data in a Spark DataFrame and use the power of generative AI in Spark.
- For example, you can ask the count of the number of records in the dataset:
We get the following response:
Spark AI internally uses LangChain and SQL chain, which hide the complexity from end-users working with queries in Spark.
The notebook has a few more example scenarios to explore the power of generative AI with Apache Spark and Amazon EMR.
Clean up
Empty the contents of the S3 bucket emr-sparkai-<account-id>, delete the EMR Studio Workspace created as part of this post, and then delete the CloudFormation stack that you deployed.
Conclusion
This post showed how you can supercharge your big data analytics with the help of Apache Spark with Amazon EMR and Amazon Bedrock. The PySpark AI package allows you to derive meaningful insights from your data. It helps reduce development and analysis time, reducing time to write manual queries and allowing you to focus on your business use case.
About the Authors
 Saurabh Bhutyani is a Principal Analytics Specialist Solutions Architect at AWS. He is passionate about new technologies. He joined AWS in 2019 and works with customers to provide architectural guidance for running generative AI use cases, scalable analytics solutions and data mesh architectures using AWS services like Amazon Bedrock, Amazon SageMaker, Amazon EMR, Amazon Athena, AWS Glue, AWS Lake Formation, and Amazon DataZone.
 Harsh Vardhan is an AWS Senior Solutions Architect, specializing in analytics. He has over 8 years of experience working in the field of big data and data science. He is passionate about helping customers adopt best practices and discover insights from their data.
Automate and enhance your code security with AI-powered services
Post Syndicated from Dylan Souvage original https://aws.amazon.com/blogs/security/automate-and-enhance-your-code-security-with-ai-powered-services/
Organizations are increasingly embracing a shift-left approach when it comes to security, actively integrating security considerations into their software development lifecycle (SDLC). This shift aligns seamlessly with modern software development practices such as DevSecOps and continuous integration and continuous deployment (CI/CD), making it a vital strategy in today’s rapidly evolving software development landscape. At its core, shift left promotes a security-as-code culture, where security becomes an integral part of the entire application lifecycle, starting from the initial design phase and extending all the way through to deployment. This proactive approach to security involves seamlessly integrating security measures into the CI/CD pipeline, enabling automated security testing and checks at every stage of development. Consequently, it accelerates the process of identifying and remediating security issues.
By identifying security vulnerabilities early in the development process, you can promptly address them, leading to significant reductions in the time and effort required for mitigation. Amazon Web Services (AWS) encourages this shift-left mindset, providing services that enable a seamless integration of security into your DevOps processes, fostering a more robust, secure, and efficient system. In this blog post we share how you can use Amazon CodeWhisperer, Amazon CodeGuru, and Amazon Inspector to automate and enhance code security.
CodeWhisperer is a versatile, artificial intelligence (AI)-powered code generation service that delivers real-time code recommendations. This innovative service plays a pivotal role in the shift-left strategy by automating the integration of crucial security best practices during the early stages of code development. CodeWhisperer is equipped to generate code in Python, Java, and JavaScript, effectively mitigating vulnerabilities outlined in the OWASP (Open Web Application Security Project) Top 10. It uses cryptographic libraries aligned with industry best practices, promoting robust security measures. Additionally, as you develop your code, CodeWhisperer scans for potential security vulnerabilities, offering actionable suggestions for remediation. This is achieved through generative AI, which creates code alternatives to replace identified vulnerable sections, enhancing the overall security posture of your applications.
Next, you can perform further vulnerability scanning of code repositories and supported integrated development environments (IDEs) with Amazon CodeGuru Security. CodeGuru Security is a static application security tool that uses machine learning to detect security policy violations and vulnerabilities. It provides recommendations for addressing security risks and generates metrics so you can track the security health of your applications. Examples of security vulnerabilities it can detect include resource leaks, hardcoded credentials, and cross-site scripting.
Finally, you can use Amazon Inspector to address vulnerabilities in workloads that are deployed. Amazon Inspector is a vulnerability management service that continually scans AWS workloads for software vulnerabilities and unintended network exposure. Amazon Inspector calculates a highly contextualized risk score for each finding by correlating common vulnerabilities and exposures (CVE) information with factors such as network access and exploitability. This score is used to prioritize the most critical vulnerabilities to improve remediation response efficiency. When started, it automatically discovers Amazon Elastic Compute Cloud (Amazon EC2) instances, container images residing in Amazon Elastic Container Registry (Amazon ECR), and AWS Lambda functions, at scale, and immediately starts assessing them for known vulnerabilities.
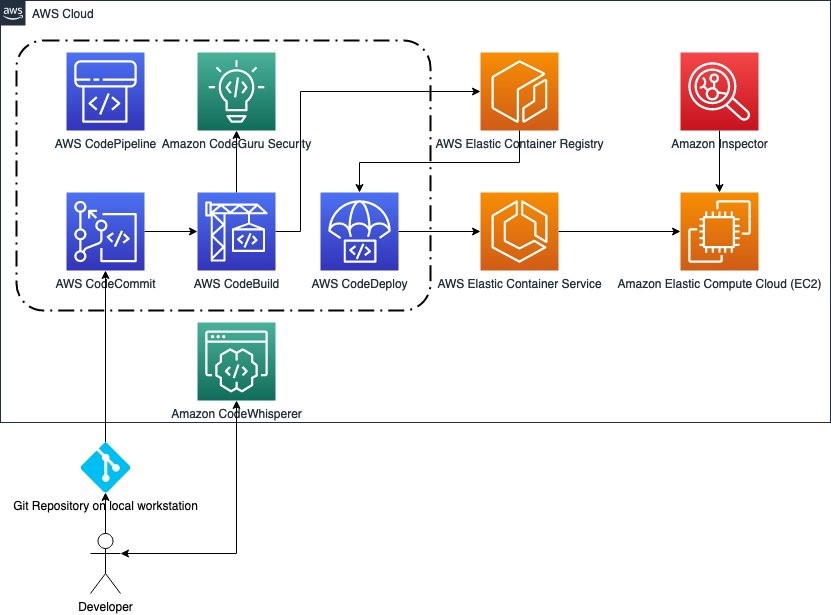
Figure 1: An architecture workflow of a developer’s code workflow
Amazon CodeWhisperer
CodeWhisperer is powered by a large language model (LLM) trained on billions of lines of code, including code owned by Amazon and open-source code. This makes it a highly effective AI coding companion that can generate real-time code suggestions in your IDE to help you quickly build secure software with prompts in natural language. CodeWhisperer can be used with four IDEs including AWS Toolkit for JetBrains, AWS Toolkit for Visual Studio Code, AWS Lambda, and AWS Cloud9.
After you’ve installed the AWS Toolkit, there are two ways to authenticate to CodeWhisperer. The first is authenticating to CodeWhisperer as an individual developer using AWS Builder ID, and the second way is authenticating to CodeWhisperer Professional using the IAM Identity Center. Authenticating through AWS IAM Identity Center means your AWS administrator has set up CodeWhisperer Professional for your organization to use and provided you with a start URL. AWS administrators must have configured AWS IAM Identity Center and delegated users to access CodeWhisperer.
As you use CodeWhisperer it filters out code suggestions that include toxic phrases (profanity, hate speech, and so on) and suggestions that contain commonly known code structures that indicate bias. These filters help CodeWhisperer generate more inclusive and ethical code suggestions by proactively avoiding known problematic content. The goal is to make AI assistance more beneficial and safer for all developers.
CodeWhisperer can also scan your code to highlight and define security issues in real time. For example, using Python and JetBrains, if you write code that would write unencrypted AWS credentials to a log — a bad security practice — CodeWhisperer will raise an alert. Security scans operate at the project level, analyzing files within a user’s local project or workspace and then truncating them to create a payload for transmission to the server side.
For an example of CodeGuru in action, see Security Scans. Figure 2 is a screenshot of a CodeGuru scan.

Figure 2: CodeWhisperer performing a security scan in Visual Studio Code
Furthermore, the CodeWhisperer reference tracker detects whether a code suggestion might be similar to particular CodeWhisperer open source training data. The reference tracker can flag such suggestions with a repository URL and project license information or optionally filter them out. Using CodeWhisperer, you improve productivity while embracing the shift-left approach by implementing automated security best practices at one of the principal layers—code development.
CodeGuru Security
Amazon CodeGuru Security significantly bolsters code security by harnessing the power of machine learning to proactively pinpoint security policy violations and vulnerabilities. This intelligent tool conducts a thorough scan of your codebase and offers actionable recommendations to address identified issues. This approach verifies that potential security concerns are corrected early in the development lifecycle, contributing to an overall more robust application security posture.
CodeGuru Security relies on a set of security and code quality detectors crafted to identify security risks and policy violations. These detectors empower developers to spot and resolve potential issues efficiently.
CodeGuru Security allows manual scanning of existing code and automating integration with popular code repositories like GitHub and GitLab. It establishes an automated security check pipeline through either AWS CodePipeline or Bitbucket Pipeline. Moreover, CodeGuru Security integrates with Amazon Inspector Lambda code scanning, enabling automated code scans for your Lambda functions.
Notably, CodeGuru Security doesn’t just uncover security vulnerabilities; it also offers insights to optimize code efficiency. It identifies areas where code improvements can be made, enhancing both security and performance aspects within your applications.
Initiating CodeGuru Security is a straightforward process, accessible through the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS SDKs, and multiple integrations. This allows you to run code scans, review recommendations, and implement necessary updates, fostering a continuous improvement cycle that bolsters the security stance of your applications.
Use Amazon CodeGuru to scan code directly and in a pipeline
Use the following steps to create a scan in CodeGuru to scan code directly and to integrate CodeGuru with AWS CodePipeline.
Note: You must provide sample code to scan.
Scan code directly
- Open the AWS Management Console using your organization management account and go to Amazon CodeGuru.
- In the navigation pane, select Security and then select Scans.
- Choose Create new scan to start your manual code scan.

Figure 3: Scans overview
- On the Create Scan page:
- Choose Choose file to upload your code.
Note: The file must be in .zip format and cannot exceed 5 GB.
- Enter a unique name to identify your scan.
- Choose Create scan.

Figure 4: Create scan
- Choose Choose file to upload your code.
- After you create the scan, the configured scan will automatically appear in the Scans table, where you see the Scan name, Status, Open findings, Date of last scan, and Revision number (you review these findings later in the Findings section of this post).
Figure 5: Scan update


Automated scan using AWS CodePipeline integration
- Still in the CodeGuru console, in the navigation pane under Security, select Integrations. On the Integrations page, select Integration with AWS CodePipeline. This will allow you to have an automated security scan inside your CI/CD pipeline.
Figure 6: CodeGuru integrations
- Next, choose Open template in CloudFormation to create a CodeBuild project to allow discovery of your repositories and run security scans.
Figure 7: CodeGuru and CodePipeline integration
- The CloudFormation template is already entered. Select the acknowledge box, and then choose Create stack.
Figure 8: CloudFormation quick create stack
- If you already have a pipeline integration, go to Step 2 and select CodePipeline console. If this is your first time using CodePipeline, this blog post explains how to integrate it with AWS CI/CD services.
Figure 9: Integrate with AWS CodePipeline
- Choose Edit.
Figure 10: CodePipeline with CodeGuru integration
- Choose Add stage.
Figure 11: Add Stage in CodePipeline
- On the Edit action page:
- Enter a stage name.
- For the stage you just created, choose Add action group.
- For Action provider, select CodeBuild.
- For Input artifacts, select SourceArtifact.
- For Project name, select CodeGuruSecurity.
- Choose Done, and then choose Save.
Figure 12: Add action group


Test CodeGuru Security
You have now created a security check stage for your CI/CD pipeline. To test the pipeline, choose Release change.
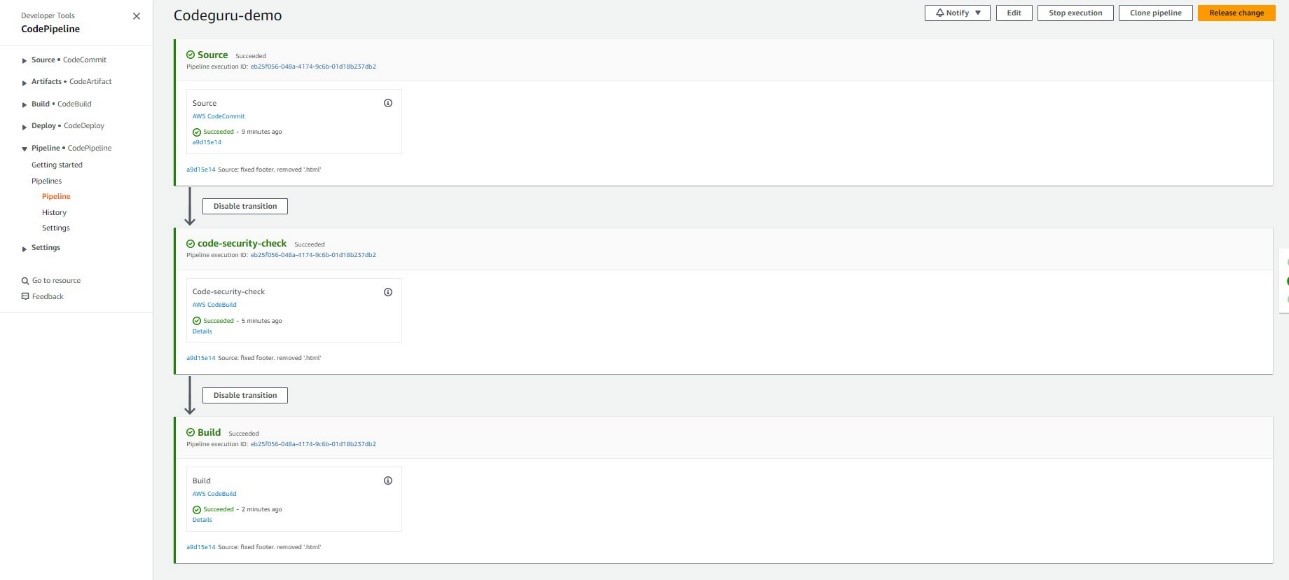
Figure 13: CodePipeline with successful security scan
If your code was successfully scanned, you will see Succeeded in the Most recent execution column for your pipeline.
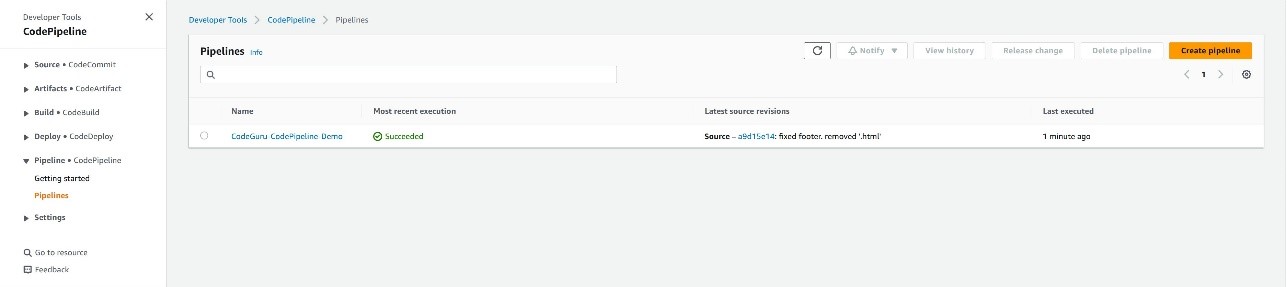
Figure 14: CodePipeline dashboard with successful security scan
Findings
To analyze the findings of your scan, select Findings under Security, and you will see the findings for the scans whether manually done or through integrations. Each finding will show the vulnerability, the scan it belongs to, the severity level, the status of an open case or closed case, the age, and the time of detection.
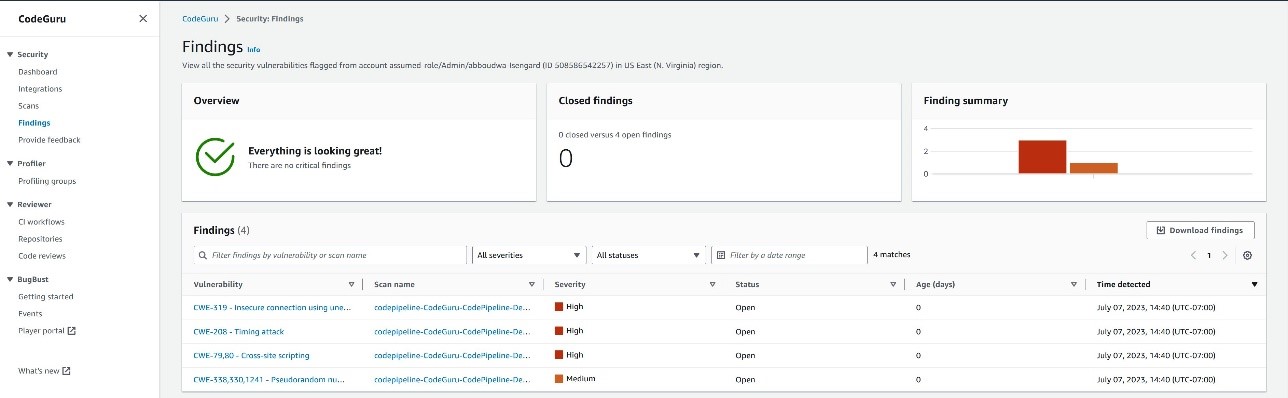
Figure 15: Findings inside CodeGuru security
Dashboard
To view a summary of the insights and findings from your scan, select Dashboard, under Security, and you will see high level summary of your findings overview and a vulnerability fix overview.
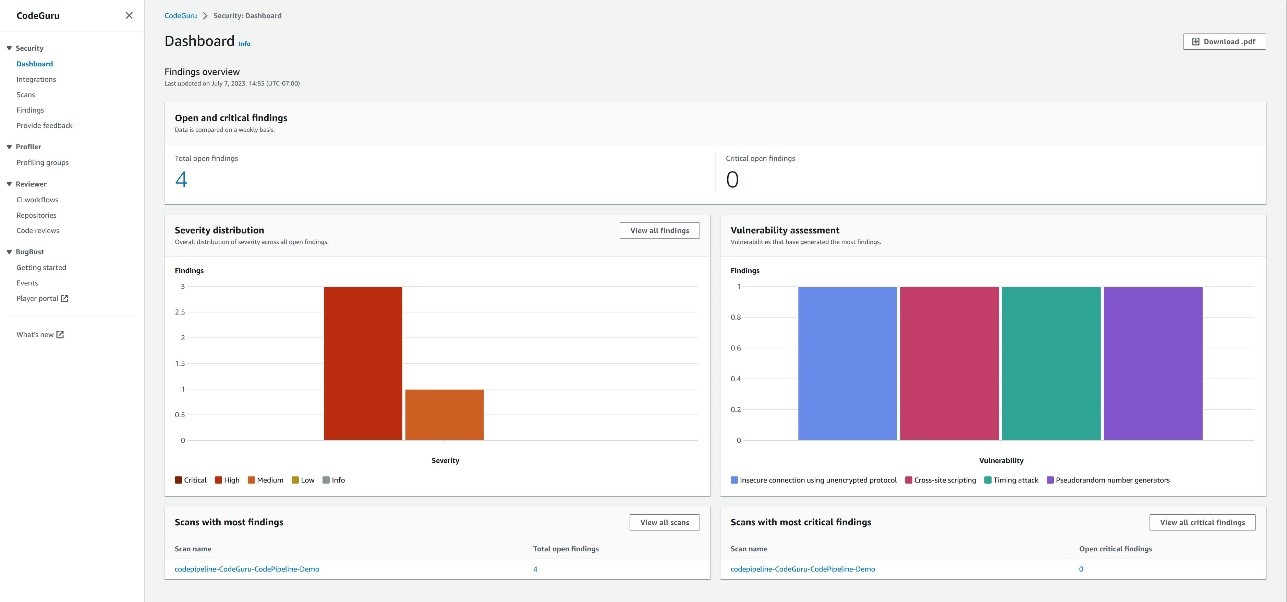
Figure 16:Findings inside CodeGuru dashboard
Amazon Inspector
Your journey with the shift-left model extends beyond code deployment. After scanning your code repositories and using tools like CodeWhisperer and CodeGuru Security to proactively reduce security risks before code commits to a repository, your code might still encounter potential vulnerabilities after being deployed to production. For instance, faulty software updates can introduce risks to your application. Continuous vigilance and monitoring after deployment are crucial.
This is where Amazon Inspector offers ongoing assessment throughout your resource lifecycle, automatically rescanning resources in response to changes. Amazon Inspector seamlessly complements the shift-left model by identifying vulnerabilities as your workload operates in a production environment.
Amazon Inspector continuously scans various components, including Amazon EC2, Lambda functions, and container workloads, seeking out software vulnerabilities and inadvertent network exposure. Its user-friendly features include enablement in a few clicks, continuous and automated scanning, and robust support for multi-account environments through AWS Organizations. After activation, it autonomously identifies workloads and presents real-time coverage details, consolidating findings across accounts and resources.
Distinguishing itself from traditional security scanning software, Amazon Inspector has minimal impact on your fleet’s performance. When vulnerabilities or open network paths are uncovered, it generates detailed findings, including comprehensive information about the vulnerability, the affected resource, and recommended remediation. When you address a finding appropriately, Amazon Inspector autonomously detects the remediation and closes the finding.
The findings you receive are prioritized according to a contextualized Inspector risk score, facilitating prompt analysis and allowing for automated remediation.
Additionally, Amazon Inspector provides robust management APIs for comprehensive programmatic access to the Amazon Inspector service and resources. You can also access detailed findings through Amazon EventBridge and seamlessly integrate them into AWS Security Hub for a comprehensive security overview.
Scan workloads with Amazon Inspector
Use the following examples to learn how to use Amazon Inspector to scan AWS workloads.
- Open the Amazon Inspector console in your AWS Organizations management account. In the navigation pane, select Activate Inspector.
- Under Delegated administrator, enter the account number for your desired account to grant it all the permissions required to manage Amazon Inspector for your organization. Consider using your Security Tooling account as delegated administrator for Amazon Inspector. Choose Delegate. Then, in the confirmation window, choose Delegate again. When you select a delegated administrator, Amazon Inspector is activated for that account. Now, choose Activate Inspector to activate the service in your management account.
Figure 17: Set the delegated administrator account ID for Amazon Inspector
- You will see a green success message near the top of your browser window and the Amazon Inspector dashboard, showing a summary of data from the accounts.
Figure 18: Amazon Inspector dashboard after activation


Explore Amazon Inspector
- From the Amazon Inspector console in your delegated administrator account, in the navigation pane, select Account management. Because you’re signed in as the delegated administrator, you can enable and disable Amazon Inspector in the other accounts that are part of your organization. You can also automatically enable Amazon Inspector for new member accounts.
Figure 19: Amazon Inspector account management dashboard
- In the navigation pane, select Findings. Using the contextualized Amazon Inspector risk score, these findings are sorted into several severity ratings.
- The contextualized Amazon Inspector risk score is calculated by correlating CVE information with findings such as network access and exploitability.
- This score is used to derive severity of a finding and prioritize the most critical findings to improve remediation response efficiency.
Figure 20: Findings in Amazon Inspector sorted by severity (default)
When you enable Amazon Inspector, it automatically discovers all of your Amazon EC2 and Amazon ECR resources. It scans these workloads to detect vulnerabilities that pose risks to the security of your compute workloads. After the initial scan, Amazon Inspector continues to monitor your environment. It automatically scans new resources and re-scans existing resources when changes are detected. As vulnerabilities are remediated or resources are removed from service, Amazon Inspector automatically updates the associated security findings.
In order to successfully scan EC2 instances, Amazon Inspector requires inventory collected by AWS Systems Manager and the Systems Manager agent. This is installed by default on many EC2 instances. If you find some instances aren’t being scanned by Amazon Inspector, this might be because they aren’t being managed by Systems Manager.
- Select a findings title to see the associated report.
- Each finding provides a description, severity rating, information about the affected resource, and additional details such as resource tags and how to remediate the reported vulnerability.
- Amazon Inspector stores active findings until they are closed by remediation. Findings that are closed are displayed for 30 days.
Figure 21: Amazon Inspector findings report details


Integrate CodeGuru Security with Amazon Inspector to scan Lambda functions
Amazon Inspector and CodeGuru Security work harmoniously together. CodeGuru Security is available through Amazon Inspector Lambda code scanning. After activating Lambda code scanning, you can configure automated code scans to be performed on your Lambda functions.
Use the following steps to configure Amazon CodeGuru Security with Amazon Inspector Lambda code scanning to evaluate Lambda functions.
- Open the Amazon Inspector console and select Account management from the navigation pane.
- Select the AWS account you want to activate Lambda code scanning in.
Figure 22: Activating AWS Lambda code scanning from the Amazon Inspector Account management console
- Choose Activate and select AWS Lambda code scanning.

With Lambda code scanning activated, security findings for your Lambda function code will appear in the All findings section of Amazon Inspector.
Amazon Inspector plays a crucial role in maintaining the highest security standards for your resources. Whether you’re installing a new package on an EC2 instance, applying a software patch, or when a new CVE affecting a specific resource is disclosed, Amazon Inspector can assist with quick identification and remediation.
Conclusion
Incorporating security at every stage of the software development lifecycle is paramount and requires that security be a consideration from the outset. Shifting left enables security teams to reduce overall application security risks.
Using these AWS services — Amazon CodeWhisperer, Amazon CodeGuru and Amazon Inspector — not only aids in early risk identification and mitigation, it empowers your development and security teams, leading to more efficient and secure business outcomes.
For further reading, check out the AWS Well Architected Security Pillar, the Generative AI on AWS page, and more blogs like this on the AWS Security Blog page.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the Amazon CodeWhisperer re:Post forum or contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
[$] The real realtime preemption end game
Post Syndicated from corbet original https://lwn.net/Articles/951337/
The addition of realtime support to Linux is a long story; it first
shows up in LWN in 2004. For much of that
time, it has seemed like only a little more work was needed to get across
the finish line; thus we ran headlines like the
realtime preemption endgame — in 2009. At the 2023 Linux Plumbers Conference, Thomas
Gleixner informed the group that, now, the end truly is near. There is
really only one big problem left to be solved before all of that work can
land in the mainline.
Security updates for Thursday
Post Syndicated from corbet original https://lwn.net/Articles/951681/
Security updates have been issued by Debian (chromium and openvpn), Oracle (kernel, microcode_ctl, plexus-archiver, and python), Red Hat (.NET 6.0, dotnet6.0, dotnet7.0, dotnet8.0, kernel, linux-firmware, and open-vm-tools), SUSE (apache2, chromium, jhead, postgresql12, postgresql13, and qemu), and Ubuntu (dotnet6, dotnet7, dotnet8, frr, python-pip, quagga, and tidy-html5).
Leaving Authentication Credentials in Public Code
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/11/leaving-authentication-credentials-in-public-code.html
Interesting article about a surprisingly common vulnerability: programmers leaving authentication credentials and other secrets in publicly accessible software code:
Researchers from security firm GitGuardian this week reported finding almost 4,000 unique secrets stashed inside a total of 450,000 projects submitted to PyPI, the official code repository for the Python programming language. Nearly 3,000 projects contained at least one unique secret. Many secrets were leaked more than once, bringing the total number of exposed secrets to almost 57,000.
[…]
The credentials exposed provided access to a range of resources, including Microsoft Active Directory servers that provision and manage accounts in enterprise networks, OAuth servers allowing single sign-on, SSH servers, and third-party services for customer communications and cryptocurrencies. Examples included:
- Azure Active Directory API Keys
- GitHub OAuth App Keys
- Database credentials for providers such as MongoDB, MySQL, and PostgreSQL
- Dropbox Key
- Auth0 Keys
- SSH Credentials
- Coinbase Credentials
- Twilio Master Credentials.
Celebrating the community: St Joseph’s Secondary School
Post Syndicated from Sophie Ashford original https://www.raspberrypi.org/blog/celebrating-the-community-st-josephs/
In our series of community stories, we celebrate some of the amazing young people and educators who are using their passion for technology to create positive change in the world around them.
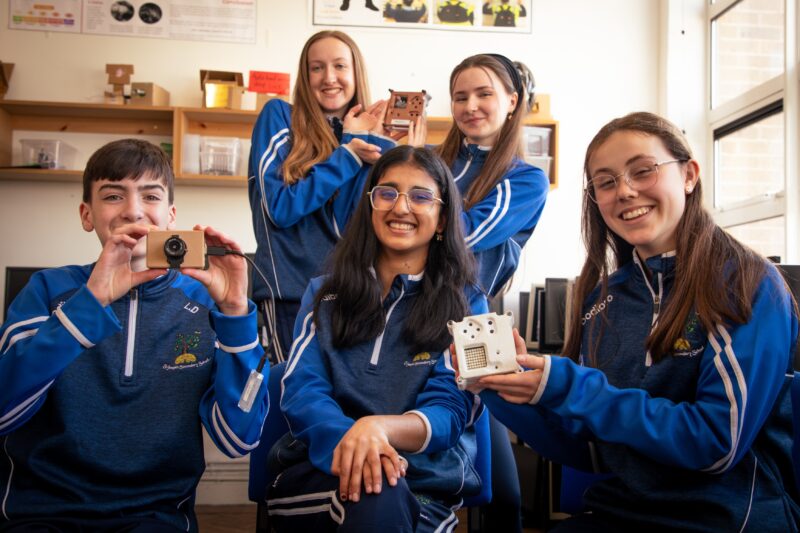
In our latest story, we’re sharing the inspiring journey of St Joseph’s Secondary School in Rush, Ireland. Over the past few years, the school community has come together to encourage coding and digital skills, harnessing the European Astro Pi Challenge as an opportunity to kindle students’ enthusiasm for tech and teamwork.
We caught up with some of the educators and students at St Joseph’s, fresh off the success of their participation in another round of Astro Pi, to delve a little deeper into the school’s focus on making opportunities to engage with computing technologies accessible to all.
Introducing St Joseph’s Secondary School
St Joseph’s Secondary School is in the heart of Rush, a rural town steeped in agricultural heritage. The school houses a diverse student population coming from the local multigenerational farming families as well as families who’ve been drawn to Rush more recently by its beautiful countryside and employment opportunities. St Joseph’s leadership team has responded to the changing demographics and increase of its student population by adapting and growing the school’s curriculum to meet the evolving needs of the young people and help them build a strong community.
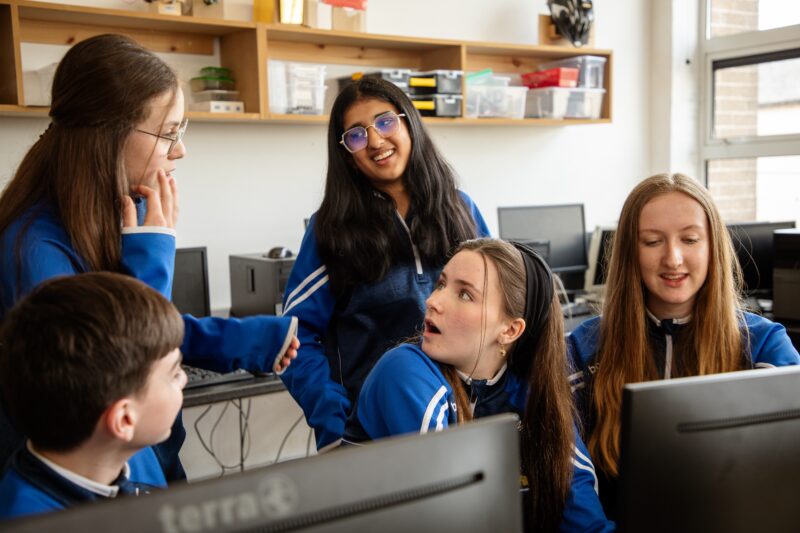
One of the school’s most popular initiatives has been teaching coding from first year (ages 12–13). This proactive approach has resonated with many students, including Kamaya, a member of the school’s 2022/23 Astro Pi cohort, who first discovered her passion for space science and computing through the movie Interstellar.
I remember the first time I was like, ‘OK, space is cool’ is when I watched a movie. It was called Interstellar. I [realised] I might want to do something like that in my future. So, when I came to [St Joseph’s] secondary school, I saw coding as a subject and I was like, ‘Mum, I’ve got to do coding.’
Kamaya, student at St Joseph’s
Inspiring students to build community through Astro Pi
A key person encouraging St Joseph’s students to give coding a try has been Mr Murray, or Danny as he is fondly referred to by students and staff alike. Danny was introduced to the importance of engaging with computing technologies while teaching science at a school in England: he attended a Code Club where he saw kids building projects with Raspberry Pis, and he couldn’t wait to get involved. Growing his knowledge from there, Danny changed subject focus when he moved back to Ireland. He took on the challenge of helping St Joseph’s expand their computer science offering, along with leading on all IT-related issues.
When the school introduced mandatory coding taster sessions for all first-year students, Danny was blown away by the students’ eagerness and wanted to provide further opportunities for them to see what they could achieve with digital technologies.
This is where Astro Pi came in. After hearing about this exciting coding challenge through an acquaintance, Danny introduced it to his computer science class, as well as extending an open invitation to all St Joseph’s students. The uptake was vast, especially once he shared that the young people could become the recipients of some very exciting photos.
You get to see photos of Earth that nobody has ever seen. Imagine just talking to somebody and saying, ‘Oh, there’s a picture of the Amazon. I took that picture when I was 14. From space.’
Danny Murray, computing teacher at St Joseph’s
Danny’s mission is to instil in his students the belief that they can achieve anything. Collaborating on Astro Pi projects has enabled young people at St Joseph’s to team up and uncover their strengths, and has helped foster a strong community.
A culture of digital skills
The students’ sense of community has transcended Danny’s classroom, creating a culture of enthusiasm for digital skills at St Joseph’s. Today, a dedicated team of students is in charge of solving tech-related challenges within the school, as Deputy Principal Darren Byrne explains:
Our own students actually go class to class, repairing tech issues. So, every day there are four or five students going around checking PCs in classrooms. They […] give classes to our first-year students on app usage.
It’s invested in the whole school [now], the idea that students can look after this kind of technology themselves. We’re the ones reaching out for help from the students!Darren Byrne, Deputy Principal at St Joseph’s
Spark enthusiasm in your school community
To find out how you can get involved in Astro Pi, visit astro-pi.org for further information, deadlines, and more. If you would like to learn more about the other free resources we have available to help you inspire a coding community in your school, head to www.raspberrypi.org/teach.
Help us celebrate St Joseph’s Secondary School by sharing their story on X (formerly Twitter), LinkedIn, and Facebook.
The post Celebrating the community: St Joseph’s Secondary School appeared first on Raspberry Pi Foundation.
На второ четене: „Алкохолен делир“
Post Syndicated from Стефан Иванов original https://www.toest.bg/na-vtoro-chetene-alkoholen-delir/
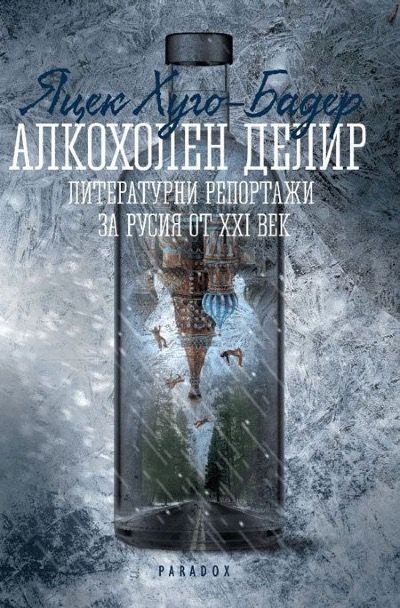
„Алкохолен делир“ от Яцек Хуго-Бадер

подзаглавие „Литературни репортажи за Русия от XXI век“, превод от полски Диляна Денчева, изд. „Парадокс“, 2019
Това е книга, написана след продължило 13 000 километра с УАЗ-ка пътешествие из Русия и стигнало до замръзналото сърце на Сибир. Книга, която те засмуква и приковава така, както се гледа пожар, изригване на вулкан, катаклизъм или нещо неочаквано и почти необяснимо – като скорошното червено северно сияние в небето на България.
Мариуш Шчигел е напълно прав, когато пише:
Ришард Капушчински описа империята от птичи полет; хвана механизмите на мислене и поведение, на процесите. Хуго-Бадер описва империята от перспективата на скитащо куче; хваща механизмите на мислене и поведение, на процесите, а също и плъха за опашката.
Яцек Хуго-Бадер е близък не само с Капушчински или с останалите забележителни представители на полския литературен репортаж, като Витолд Шабловски, споменатия Шчигел или Кшищоф Варга, всичките преведени и на български. Той се родее не само заради темите си, но и заради любопитството, смелостта и професионализма си, и с нобеловата лауреатка Светлана Алексиевич. Както нейните книги, така и неговите не целят да шокират или експлоатират, а да показват невидимото и заметеното. Това, което откровената пропаганда на властта не признава, че съществува.
Четенето на такива книги е друга форма на откровение и като такава е и апокалиптична.
Показва всекидневния апокалипсис в Русия чрез пътешествие от Варшава до Владивосток.
Но това не е тежко четиво, напротив. Мрачният му хумор и ирония, цапнатата му уста и безкрайните отклонения и коментари го доближават и до Хънтър С. Томпсън, а по някакъв начин и до Венедикт Ерофеев.
Идеята му хрумва, след като прочита съветската колективна научна творба „Репортаж от ХХІ век“ (1957 г.), фантазираща в детайли каква точно ще е реализираната съветска утопия през 2007 г. Полският писател и журналист решава като подарък за собствения си петдесети рожден ден да обиколи Русия с тази книга и да сравнява доколко са се сбъднали прогнозите: за електрическите автомобили, лунните заселници, чистотата на Москва, изчезналите болести, унищожението на метеорити от космически кораби, отказа от оръжия и общото благосъстояние на съветските земи и населението им.
Отбелязал съм си по нещо от почти всяка страница на това пътешествие. Още в началото се сетих за пасаж от „Москва-Петушки“ на Ерофеев:
… не знаех, че на тоя свят имало такава болка. Сгърчих се от мъка, гъстата червена буква Ю се разля пред очите ми и затрепка. И оттогава не съм идвал в съзнание и никога няма да дойда.
Хуго-Бадер обаче се е върнал в съзнание и е минал през цялата азбука, стигнал е до Я и е продължил нататък.
Питах се защо толкова ме впечатли това безумно антропологично изследване, този предълъг документален филм, който се точи пред очите ми. Първо, защото всъщност не познавам Русия. Не съм наясно със страната по никакъв начин, не знам езика, не съм на ти със сленга, нито с културата и със субкултурата ѝ. Четенето на Пелевин, Ирина Денежкина или Анна Старобинец не са достатъчни.
Второ, има една официална представа, за която съм чел и слушал – лагерите, примерите за интелектуална или артистична съпротива. Неофициалната и всекидневната представа обаче не познавам. А книгата на Хуго-Бадер запълва този дефицит. Тя загребва без уплаха от дъното и под него, от социалните дълбини, центрове и покрайнини на Русия. Вади срещи и разговори с хора, оцелели, радващи се, провалящи се, историите им са парчета злато, патинирано със страдание, надежда, безнадеждност и кръв.
Пътуването започва от Сибир и от една ледена версия на свят, познат от филмите за Лудия Макс – с бункери, стрелби и убийства на пътя, със срещи с корумпирани полицаи и милиционери в страната, където до 2010 г. Десети ноември е Ден на милиционера. Пътят прекосява света на рапъри и агресивните им практики и скандали, на анархисти, антифашисти и хипита, на болни от СПИН и наркомани, на проститутки, ченгета и политици.
Хуго-Бадер не се свени, нито се притеснява от събеседниците си. Внимателно събира важни понятия и думи в речник – съществена част от книгата. Хората разговарят открито с него, защото и той е откровен с тях, а е и виртуоз в изкуството на човешкото общуване и разбиране. Помага на събеседниците да споделят историите си, за да се преутвърдят, да заблести достойнството на това, че са живи, макар и в страна, пропита от провал и белязана от естетиката на бедността и дефицита на щастие.
Хуго-Бадер е такъв, независимо дали ни среща с алкохолици, психиатри, шамани, миньори, професори и археолози. Или с евенки, улчи, нанайци, удегейци и други коренни жители на руските земи. Той успява да открие и единственото място в Русия, където среща главно щастливи хора – сектата на Висарион, преродения Исус, който понастоящем от три години е в затвора.
Естествено, става дума и за Путин:
След три години двамата анархисти излезли от затвора и обяснили, че Виктор не е можел да ги предаде, защото нищо не знаел за тяхната дейност. Жена му поискала да се върне, но Виктор не могъл да преживее факта, че не му повярвала.
– И знаеш ли чия беше тази операция? – пита ме Виктор.
– Е?
– На Владимир Путин.
– Ебаваш се!
– Беше младши лейтенант и в ленинградското КГБ отговаряше за неформалните младежки групи – казва Виктор. – Привикваше ни и лично водеше разпитите.
– Маризил ли те е?
– Нито веднъж. Другите биеха като бесни, изпотрошиха ми пръстите, осакатиха ме, избиха ми зъбите, а той нито ругатни, нито заплахи. Няма от какво да се срамува.
– Прекаляваш! Съсипал ти е живота!
– И на жена ми не ѝ провървя. Остана сама, а синът ни израсна без нормално семейство. На трийсет и една е и е наркоман. Единственото ми дете. На всичките ни съсипа живота.
В разговор от 2014 г. Хуго-Бадер накратко обяснява и защо и как е възможен Путин:
Руснаците го смятат за човек, който ги изправя, след като Горбачов и Елцин ги събориха на колене след падането на СССР. Путин ги кара да се гордеят. Това е много важно чувство за руснаците, защото те винаги са живели в държава, която им дава единствено него. Едва се преживява, няма какво да се яде, какво да се пие, тъй като ни въвеждат „сухой закон“, човек се страхува от всичко, трепери за живота си, но едно му е гарантирано – може да се гордее със своята велика империя, от която всички се страхуват. Тази мощ се крепи на три елемента: могъщата армия, каквато няма никой друг на света (само танкове в армията на СССР има толкова, колкото във всички армии по света, взети заедно), космическите полети и спортистите, които си тръгват с половината медали от всяка олимпиада. Горбачов и Елцин им отнеха дори и това, а Путин им го връща.
Ще е много ценно Хуго-Бадер да има възможността и енергията да отиде в Русия след Путин и отново да ни срещне с хората там. Наистина е забележително как в писането му думата е дадена именно на хората. Не се говори за тях – говорят те самите и изказват едно след друго толкова неназовими неща. Това не е кабинетна и аналитична книга. Авторът е на бойното поле, каквото е животът за гражданите на Русия и преди войната. Това не е интелектуално заключение, а емоционално. И съм убеден, че само с такова писане може да се стигне до промяна в представата и нагласата, в разбирането на една болка и в произхода и причините ѝ – икономически, социални и политически.
Такъв почерк и отношение не идват от само себе си. Авторът не е просто журналист в „Газета виборча“, не седи пред лаптопа си и не разсъждава абстрактно и ерудирано. Бил е учител, товарач на влак, продавач на свински пазар, дистрибутор, магазинер и част от „Солидарност“, когато профсъюзът е била нелегална структура. Минал е на колело през Централна Азия, пустинята Гоби и Китай, преплувал е езерото Байкал с кану, автор е на документални филми и е двукратен носител на полската награда за най-добър журналист.
Толкова ми липсват такива фигури и репортажи на български – за обикновени хора, в които под повърхността се таи цялата възможна необикновеност и необяснимост на България.
Преди години такива текстове и срещи чаках всеки месец от Ина Григорова и от списание „Егоист“. Вярвам например, че някоя от следващите книги на Димитър Кенаров ще е с репортажи от България. А съм и сигурен, че българската журналистика отново ще се престраши и няма да се притеснява да се оцапа, за да извади страната си на светло не само с политически коментари и разследвания, но и с литературни репортажи. Има предостатъчно високи, иронични и умни упражнения по стил, нужно е да се излезе навън и да се погледне наоколо, даже и надолу – в реалността и конкретиката.
Това трябва да се случи, защото, както казва Хуго-Бадер,
журналистиката съществува, за да бъде светът по-добър. Не си представям нито една държава, нито една демокрация без медии. Новинарите, информационните медии разказват какво се случва, репортажът отговаря на въпроса защо е така.
Репортажът е рапорт и негов дълг е той да бъде даден, приет и прочетен.
Активните дарители на „Тоест“ получават постоянна отстъпка в размер на 20% от коричната цена на всички заглавия от каталога на издателство „Парадокс“, както и на няколко други български издателства в рамките на партньорската програма Читателски клуб „Тоест“. За повече информация прочетете на toest.bg/club.
Никой от нас не чете единствено най-новите книги. Тогава защо само за тях се пише? „На второ четене“ е рубрика, в която отваряме списъците с книги, публикувани преди поне година, четем ги и препоръчваме любимите си от тях. Рубриката е част от партньорската програма Читателски клуб „Тоест“. Изборът на заглавия обаче е единствено на авторите – Стефан Иванов и Антония Апостолова, които биха ви препоръчали тези книги и ако имаше как веднъж на две седмици да се разходите с тях в книжарницата.
[$] LWN.net Weekly Edition for November 16, 2023
Post Syndicated from corbet original https://lwn.net/Articles/950829/
The LWN.net Weekly Edition for November 16, 2023 is available.
Introducing instance maintenance policy for Amazon EC2 Auto Scaling
Post Syndicated from Macey Neff original https://aws.amazon.com/blogs/compute/introducing-instance-maintenance-policy-for-amazon-ec2-auto-scaling/
This post is written by Ahmed Nada, Principal Solutions Architect, Flexible Compute and Kevin OConnor, Principal Product Manager, Amazon EC2 Auto Scaling.
Amazon Web Services (AWS) customers around the world trust Amazon EC2 Auto Scaling to provision, scale, and manage Amazon Elastic Compute Cloud (Amazon EC2) capacity for their workloads. Customers have come to rely on Amazon EC2 Auto Scaling instance refresh capabilities to drive deployments of new EC2 Amazon Machine Images (AMIs), change EC2 instance types, and make sure their code is up-to-date.
Currently, EC2 Auto Scaling uses a combination of ‘launch before terminate’ and ‘terminate and launch’ behaviors depending on the replacement cause. Customers have asked for more control over when new instances are launched, so they can minimize any potential disruptions created by replacing instances that are actively in use. This is why we’re excited to introduce instance maintenance policy for Amazon EC2 Auto Scaling, an enhancement that provides customers with greater control over the EC2 instance replacement processes to make sure instances are replaced in a way that aligns with performance priorities and operational efficiencies while minimizing Amazon EC2 costs.
This post dives into varying ways to configure an instance maintenance policy and gives you tools to use it in your Amazon EC2 Auto Scaling groups.
Background
AWS launched Amazon EC2 Auto Scaling in 2009 with the goal of simplifying the process of managing Amazon EC2 capacity. Since then, we’ve continued to innovate with advanced features like predictive scaling, attribute-based instance selection, and warm pools.
A fundamental Amazon EC2 Auto Scaling capability is replacing instances based on instance health, due to Amazon EC2 Spot Instance interruptions, or in response to an instance refresh operation. The instance refresh capability allows you to maintain a fleet of healthy and high-performing EC2 instances in your Amazon EC2 Auto Scaling group. In some situations, it’s possible that terminating instances before launching a replacement can impact performance, or in the worst case, cause downtime for your applications. No matter what your requirements are, instance maintenance policy allows you to fine-tune the instance replacement process to match your specific needs.
Overview
Instance maintenance policy adds two new Amazon EC2 Auto Scaling group settings: minimum healthy percentage (MinHealthyPercentage) and maximum healthy percentage (MaxHealthyPercentage). These values represent the percentage of the group’s desired capacity that must be in a healthy and running state during instance replacement. Values for MinHealthyPercentage can range from 0 to 100 percent and from 100 to 200 percent for MaxHealthyPercentage. These settings are applied to all events that lead to instance replacement, such as Health-check based replacement, Max Instance Lifetime, EC2 Spot Capacity Rebalancing, Availability Zone rebalancing, Instance Purchase Option Rebalancing, and Instance refresh. You can also override the group-level instance maintenance policy during instance refresh operations to meet specific deployment use cases.
Before launching instance maintenance policy, an Amazon EC2 Auto Scaling group would use the previously described behaviors when replacing instances. By setting the MinHealthyPercentage of the instance maintenance policy to 100% and the MaxHealthyPercentage to a value greater than 100%, the Amazon EC2 Auto Scaling group first launches replacement instances and waits for them to become available before terminating the instances being replaced.
Setting up instance maintenance policy
You can add an instance maintenance policy to new or existing Amazon EC2 Auto Scaling groups using the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS SDK, AWS CloudFormation, and Terraform.
When creating or editing Amazon EC2 Auto Scaling groups in the Console, you are presented with four options to define the replacement behavior of your instance maintenance policy. These options include the No policy option, which allows you to maintain the default instance replacement settings that the Amazon EC2 Auto Scaling service uses today.

Image 1: The GUI for the instance maintenance policy feature within the “Create Auto Scaling group” wizard.
Using instance maintenance policy to increase application availability
The Launch before terminating policy is the right selection when you want to favor availability of your Amazon EC2 Auto Scaling group capacity. This policy setting temporarily increases the group’s capacity by launching new instances during replacement operations. In the Amazon EC2 console, you select the Launch before terminating replacement behavior, and then set your desired MaxHealthyPercentage value to determine how many more instances should be launched during instance replacement.
For example, if you are managing a workload that requires optimal availability during instance replacements, choose the Launch before terminating policy type with a MinHealthyPercentage set to 100%. If you set your MaxHealthyPercentage to 150%, then Amazon EC2 Auto Scaling launches replacement instances before terminating instances to be replaced. You should see the desired capacity increase by 50%, exceeding the group maximum capacity during the operation to provide you with the needed availability. The chart in the following figure illustrates what an instance refresh operation would behave like with a Launch before terminating policy.

Figure 1: A graph simulating the instance replacement process with a policy configured to launch before terminating.
Overriding a group’s instance maintenance policy during instance refresh
Instance maintenance policy settings apply to all instance replacement operations, but they can be overridden at the start of a new instance refresh operation. Overriding instance maintenance policy is helpful in situations like a bad code deployment that needs replacing without downtime. You could configure an instance maintenance policy to bring an entirely new group’s worth of instances into service before terminating the instances with the problematic code. In this situation, you set the MaxHealthyPercentage to 200% for the instance refresh operation and the replacement happens in a single cycle to promptly address the bad code issue. Setting the MaxHealthyPercentage to 200% will allow the replacement settings to breach the Auto Scaling Group’s Max capacity value, but would be constrained by any account level quotas, so be sure to factor these into application of this feature. See the following figure for a visualization of how this operation would behave.

Figure 2: A graph simulating the instance replacement process with a policy configured to accelerate a new deployment.
Controlling costs during replacements and deployments
The Terminate and launch policy option allows you to favor cost control during instance replacement. By configuring this policy type, Amazon EC2 Auto Scaling terminates existing instances and then launches new instances during the replacement process. To set a Terminate and launch policy, you must specify a MinHealthyPercentage to establish how low the capacity can drop, and keep your MaxHealthyPercentage set to 100%. This configuration keeps the Auto Scaling group’s capacity at or below the desired capacity setting.
The following figure shows behavior with the MinHealthyPercentage set to 80%. During the instance replacement process, the Auto Scaling group first terminates 20% of the instances and immediately launches replacement instances, temporarily reducing the group’s healthy capacity to 80%. The group waits for the new instances to pass its configured health checks and complete warm up before it moves on to replacing the remaining batches of instances.

Figure 3: A graph simulating the instance replacement process with a policy configured to terminate and launch.
Note that the difference between MinHealthyPercentage and MaxHealthyPercentage values impacts the speed of the instance replacement process. In the preceding figure, the Amazon EC2 Auto Scaling group replaces 20% of the instances in each cycle. The larger the gap between the MinHealthyPercentage and MaxHealthyPercentage, the faster the replacement process.
Using a custom policy for maximum flexibility
You can also choose to adopt a Custom behavior option, where you have the flexibility to set the MinHealthyPercentage and MinHealthyPercentage values to whatever you choose. Using this policy type allows you to fine-tune the replacement behavior and control the capacity of your instances within the Amazon EC2 Auto Scaling group to tailor the instance maintenance policy to meet your unique needs.
What about fractional replacement calculations?
Amazon EC2 Auto Scaling always favors availability when performing instance replacements. When instance maintenance policy is configured, Amazon EC2 Auto Scaling also prioritizes launching a new instance rather than going below the MinHealthyPercentage. For example, in an Amazon EC2 Auto Scaling group with a desired capacity of 10 instances and an instance maintenance policy with MinHealthyPercentage set to 99% and MaxHealthyPercentage set to 100%, your settings do not allow for a reduction in capacity of at least one instance. Therefore, Amazon EC2 Auto Scaling biases toward launch before terminating and launches one new instance before terminating any instances that need replacing.
Configuring an instance maintenance policy is not mandatory. If you don’t configure your Amazon EC2 Auto Scaling groups to use an instance maintenance policy, then there is no change in the behavior of your Amazon EC2 Auto Scaling groups’ existing instance replacement process.
You can set a group-level instance maintenance policy through your CloudFormation or Terraform templates. Within your templates, you must set values for both the MinHealthyPercentage and MaxHealthyPercentage settings to determine the instance replacement behavior that aligns with the specific requirements of your Amazon EC2 Auto Scaling group.
Conclusion
In this post, we introduced the new instance maintenance policy feature for Amazon EC2 Auto Scaling groups, explored its capabilities, and provided examples of how to use this new feature. Instance maintenance policy settings apply to all instance replacement processes with the option to override the settings on a per instance refresh basis. By configuring instance maintenance policies, you can control the launch and lifecycle of instances in your Amazon EC2 Auto Scaling groups, increase application availability, reduce manual intervention, and improve cost control for your Amazon EC2 usage.
To learn more about the feature and how to get started, refer to the Amazon EC2 Auto Scaling User Guide.
Peter Thiel Is Taking a Break From Democracy
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=U8L_MKWXcOA
New – Amazon EBS Snapshot Lock
Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-amazon-ebs-snapshot-lock/
You can now lock individual Amazon Elastic Block Store (Amazon EBS) snapshots in order to enforce better compliance with your data retention policies. Locked snapshots cannot be deleted until the lock is expired or released, giving you the power to keep critical backups safe from accidental or malicious deletion, including ransomware attacks.
The Need for Locking
AWS customers use EBS snapshots for backups, disaster recovery, data migration, and compliance. Customers in financial services and health care often need to meet specific compliance requirements, with prescribed time frames for retention, and also need to ensure that the snapshots are truly Write Once Read Many (WORM). In order to meet these requirements, customers have implemented solutions that use multiple AWS accounts with one-way “air gaps” between them.
EBS Snapshot Lock
The new EBS Snapshot Lock feature helps you to meet your retention and compliance requirements without the need for custom solutions. You can lock new and existing EBS snapshots using a lock duration that can range from one day to about 100 years. The snapshot is locked for the specified duration and cannot be deleted.
There are two lock modes:
Governance – This mode protects snapshots from deletions by all users. However, with the proper IAM permissions, the lock duration can be extended or shortened, the lock can be deleted, and the mode can be changed from Governance mode to Compliance mode.
Compliance – This mode protects snapshots from actions by the root user and all IAM users. After a cooling-off period of up to 72 hours, neither the snapshot nor the lock can be deleted until the lock duration expires, and the mode cannot be changed. With the proper IAM permissions the lock duration can be extended, but it cannot be shortened.
Snapshots in either mode can still be shared or copied. They can be archived to the low-cost Amazon EBS Snapshots Archive tier, and locks can be applied to snapshots that have already been archived.
Using Snapshot Lock
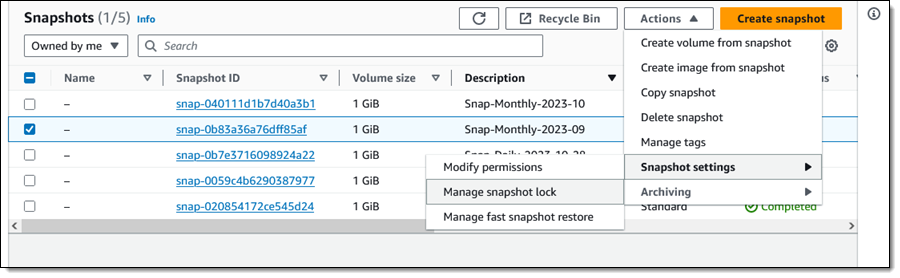
From the EBS Console I select a snapshot (Snap-Monthly-2023-09) and choose Manage snapshot lock from Snapshot Settings in the Actions menu:
This is a monthly snapshot and I want to lock it for one year. I choose Governance mode and select the duration, then click Save lock settings:

I try to delete it, and the deletion fails, as it should:
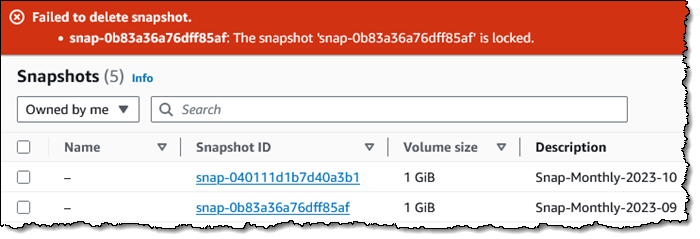
Now I would like to lock one of my annual snapshots for 5 years, using Compliance mode this time:
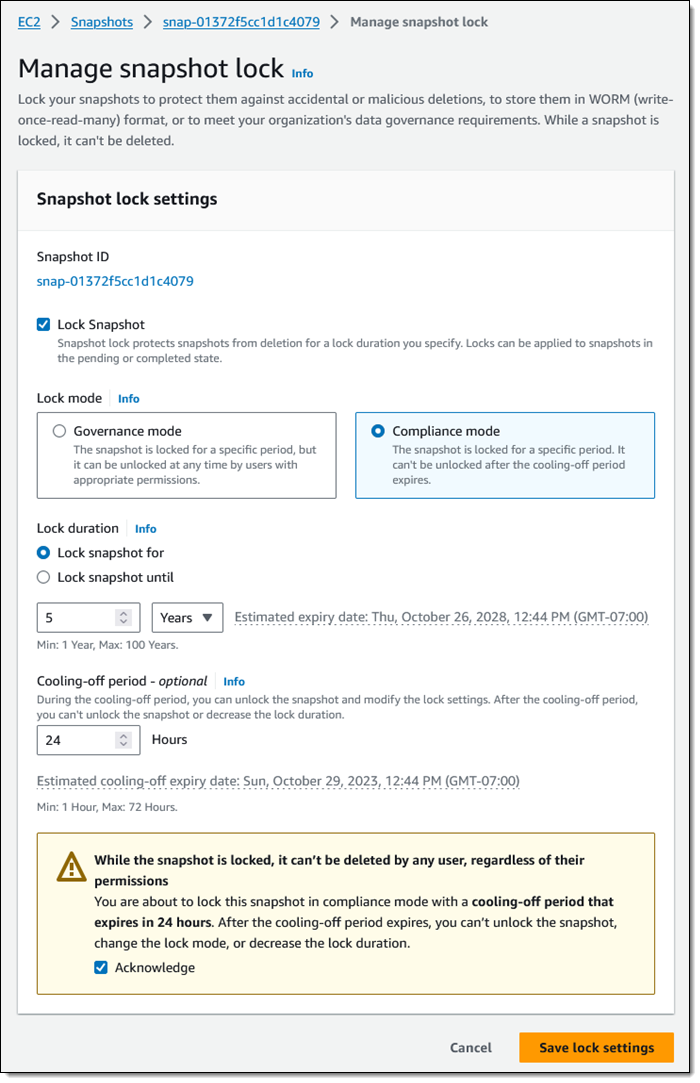
I set my cooling-off period to 24 hours, just in case I change my mind. Perhaps I have to run some kind of audit or final date validation on the snapshot before committing to keeping it around for five years.
Programmatically, I can use new API functions to establish and control locks on my EBS snapshots:
LockSnapshot – Lock a snapshot in governance or compliance mode, or modify the settings of a snapshot that is already locked.
UnlockSnapshot – Unlock a snapshot that is is governance mode, or is in compliance mode but within the cooling-off period.
DescribeLockedSnapshots – Get information about the lock status of my snapshots, with optional filtering based on the state of the lock.
IAM users must have the appropriate permissions (ec2:lockSnapshot, ec2:UnlockSnapshot, and ec2:DescribeLockedSnapshots) in order to use these functions.
Things to Know
Here are a couple of things to keep in mind about this new feature:
AWS Backup – AWS Backup independently manages retention for the snapshots that it creates. We do not recommend locking them.
Pricing – There is no extra charge for the use of this feature. You pay the usual rates for storage of snapshots and archived snapshots.
Regions – EBS Snapshot Locking is available in all commercial AWS Regions.
KMS Key Retention – If you are using customer-managed AWS Key Management Service (AWS KMS) keys to encrypt your EBS volumes and snapshots, you need to make sure that the key will remain valid for the lifetime of the snapshot.
— Jeff;
How the Stuka and Douglas SBD Altered the Course of WW2
Post Syndicated from Curious Droid original https://www.youtube.com/watch?v=xEZgaSib4FA
Microsoft Azure Eagle is a Paradigm Shifting Cloud Supercomputer
Post Syndicated from John Lee original https://www.servethehome.com/microsoft-azure-eagle-is-a-paradigm-shifting-cloud-supercomputer-nvidia-intel/
At SC23, the Microsoft Azure Eagle supercomputer made its debut as a Top 3 system and it will shift access to enormous HPC and AI compute
The post Microsoft Azure Eagle is a Paradigm Shifting Cloud Supercomputer appeared first on ServeTheHome.
[$] Faster kernel testing with virtme-ng
Post Syndicated from jake original https://lwn.net/Articles/951313/
Building new kernels and booting into them is an unavoidable—and
time-consuming—part of kernel development. Andrea Righi works for
Canonical on the Ubuntu kernel team, so he does a lot of that and wanted to
find a way to speed up the task. To that end, he has been working
on virtme-ng, which is a
way to boot a new kernel in a virtual machine, and it does
so quickly. He came to the 2023
Linux Plumbers Conference (LPC) in Richmond, Virginia to introduce the
project to a wider audience.
Ексклузивно блиц интервю с новия столичен градоначалник Васил Терзиев пред Биволъ и Либерта: Няма наши, няма ваши – ще стигнем до фирмите, които не се справят (видео)
Post Syndicated from Николай Марченко original https://bivol.bg/vasil-terziev-korupciq-bivol-liberta.html
сряда 15 ноември 2023

Новоизбраният кмет на София Васил Терзиев бе почетен гост на представянето на книгата на одитора и съосновател на Антикорупционен фонд (АКФ) Йордан Карабинов “Система за превенция на корупция и измами”…
Building sensitive data remediation workflows in multi-account AWS environments
Post Syndicated from Darren Roback original https://aws.amazon.com/blogs/security/building-sensitive-data-remediation-workflows-in-multi-account-aws-environments/
The rapid growth of data has empowered organizations to develop better products, more personalized services, and deliver transformational outcomes for their customers. As organizations use Amazon Web Services (AWS) to modernize their data capabilities, they can sometimes find themselves with data spread across several AWS accounts, each aligned to distinct use cases and business units. This can present a challenge for security professionals, who need not only a mechanism to identify sensitive data types—such as protected health information (PHI), payment card industry (PCI), and personally identifiable information (PII), or organizational intellectual property—stored on AWS, but also the ability to automatically act upon these findings through custom logic that supports organizational policies and regulatory requirements.
In this blog post, we present a solution that provides you with visibility into sensitive data residing across a fleet of AWS accounts through a ChatOps-style notification mechanism using Microsoft Teams, which also provides contextual information needed to conduct security investigations. This solution also incorporates a decision logic mechanism to automatically quarantine sensitive data assets while they’re pending review, which can be tailored to meet unique organizational, industry, or regulatory environment requirements.
Prerequisites
Before you proceed, ensure that you have the following within your environment:
- Access to a set of AWS accounts that have been joined to an organization with all features enabled.
- Logically grouped AWS Organizations member accounts into organizational units (OUs).
- Enabled AWS CloudFormation trusted access within AWS Organizations.
- Enabled tag policies within AWS Organizations.
- A designated security tooling account within AWS Organizations that’s dedicated to operating security services, monitoring AWS accounts, and automating security alerting and response, and whose access is restricted through AWS Identity and Access Management (IAM) to security professionals.
- Permissions to create the resources listed below using CloudFormation.
- A Microsoft Teams account with permissions to add apps and webhooks in your desired team and channel.
Assumptions
Things to know about the solution in this blog post:
- This solution assumes that Amazon Simple Storage Service (Amazon S3) buckets in scope for sensitive data discovery and remediation are not enabled for S3 versioning. Amazon Macie supports sensitive data discovery of current object versions, and the solution presented here automatically quarantines current object versions determined to contain sensitive data. Additional customization of this solution might be required to allow or deny access to previous object versions and delete markers.
- This solution assumes that you’ve set up your AWS accounts for IAM authentication, and the notifications presented to you in Microsoft Teams will reflect an IAM user authentication experience. If you’re using AWS IAM Identity Center with federated authentication, additional customization of this solution might be required.
Solution overview
The solution architecture and overall workflow are detailed in Figure 1 that follows.
Figure 1: Solution overview
Upon discovering sensitive data in member accounts, this solution selectively quarantines objects based on their finding severity and public status. This logic can be customized to evaluate additional details such as the finding type or number of sensitive data occurrences detected. The ability to adjust this workflow logic can provide a custom-tailored solution to meet a variety of industry use cases, helping you adhere to industry-specific security regulations and frameworks.
Figure 1 provides an overview of the components used in this solution, and for illustrative purposes we step through them here.
Automated scanning of buckets
Macie supports various scope options for sensitive data discovery jobs, including the use of bucket tags to determine in-scope buckets for scanning. Setting up automated scanning includes the use of an AWS Organizations tag policy to verify that the S3 buckets deployed in your chosen OUs conform to tagging requirements, an AWS Config job to automatically check that tags have been applied correctly, an Amazon EventBridge rule and bus to receive compliance events from a fleet of member accounts, and an AWS Lambda function to notify administrators of compliance change events.
- An AWS Organizations tag policy verifies that the S3 buckets created in the in-scope AWS accounts have a tag structure that facilitates automated scanning and identification of the bucket owner. Specific tags enforced with this tag policy include RequireMacieScan : True|False and BucketOwner : <variable>. The tag policy is enforced at the OU level.
- A custom AWS Config rule evaluates whether these tags have been applied to all in-scope S3 buckets, and marks resources as compliant or not compliant.
- After every evaluation of S3 bucket tag compliance, AWS Config will send compliance events to an EventBridge event bus in the same AWS member account.
- An EventBridge rule is used to send compliance messages from member accounts to a centralized security account, which is used for operational administration of the solution.
- An EventBridge rule in the centralized security account is used to send all tag compliance events to a Lambda serverless function, which is used for notification.
- The tag compliance notification function receives the tag compliance events from EventBridge, parses the information, and posts it to a Microsoft Teams webhook. This provides you with details such as the affected bucket, compliance status, and bucket owner, along with a link to investigate the compliance event in AWS Config.
Detecting sensitive data
Macie is a key component of this solution and facilitates sensitive data discovery across a fleet of AWS accounts based on the RequireMacieScan tag value configured at the time of bucket creation. Setting up sensitive data detection includes using Macie for sensitive data discovery, an EventBridge rule and bus to receive these finding events from the Macie delegated administrator account, an AWS Step Functions state machine to process these findings, and a Lambda function to notify administrators of new findings.
- Macie is used to detect sensitive data in member account S3 buckets with job definitions based on bucket tags, and central reporting of findings through a Macie delegated administrator account (that is, the central security account).
- When new findings are detected, Macie will send finding events to an EventBridge event bus in the security account.
- An EventBridge rule is used to send all finding events to AWS Step Functions, which runs custom business logic to evaluate each finding and determine the next action to take on the affected object.
- In the default configuration, for findings that are of low or medium severity and in objects that are not publicly accessible, Step Functions sends finding event information to a Lambda serverless function, which is used for notification. You can alter this event processing logic in Step Functions to change which finding types initiate an automated quarantine of the object.
- The Macie finding notification function receives the finding events from Step Functions, parses this information, and posts it to a Microsoft Teams webhook. This presents you with details such as the affected bucket and AWS account, finding ID and severity, public status, and bucket owner, along with a link to investigate the finding in Macie.
Automated quarantine
As outlined in the previous section, this solution uses event processing decision logic in Step Functions to determine whether to quarantine a sensitive object in place. Setting up automated quarantine includes a Step Functions state machine for Macie finding processing logic, an Amazon DynamoDB table to track items moved to quarantine, a Lambda function to notify administrators of quarantine, and an Amazon API Gateway and second Step Functions state machine to facilitate remediation or removal of objects from quarantine.
- In the default configuration for findings that are of high severity, or in objects that are publicly accessible, Step Functions adds the affected object’s metadata to an Amazon DynamoDB table, which is used to track quarantine and remediation status at scale.
- Step Functions then quarantines the affected object, moving it to an automatically configured and secured prefix in the same S3 bucket while the finding is being investigated. Only select personnel (that is, cybersecurity) has access to the object.
- Step Functions then sends finding event information to a Lambda serverless function, which is used for notification.
- The Macie quarantine notification function receives the finding events from Step Functions, parses this information, and posts it to a Microsoft Teams webhook. This presents you with similar details to the Macie finding notification function, but also notes the object has been moved to quarantine, and provides a one-click option to release the object from quarantine.
- In the Microsoft Teams channel, which should only be accessible to qualified security professionals, DLP administrators select the option to release the object from quarantine. This invokes a REST API deployed on API Gateway.
- API Gateway invokes a release object workflow in Step Functions, which begins to process releasing the affected object from quarantine.
- Step Functions inspects the affected object ID received through API Gateway, and first retrieves details about this object from DynamoDB. Upon receiving these details, the object is removed from the quarantine tracking database.
- Step Functions then moves the affected object to its original location in Amazon S3, thereby making the object accessible again under the original bucket policy and IAM permissions.
Organization structure
As mentioned in the prerequisites, the solution uses a set of AWS accounts that have been joined to an organization, which is shown in Figure 2. While the logical structure of your AWS Organizations deployment can differ from what’s shown, for illustration purposes, we’re looking for sensitive data in the Development and Production AWS accounts, and the examples shown throughout the remainder of this blog post reflect that.
Figure 2: Organization structure
Deploy the solution
The overall deployment process of this solution has been decomposed into three AWS CloudFormation templates to be deployed to your management, security, and member accounts as CloudFormation stacks and StackSets, respectively. Performing the deployment in this manner not only verifies that the solution is extended to other member accounts created after the initial solution deployment, but also serves as an illustrative aid of the components deployed in each portion of the solution. An overview of the deployment process is as follows:
- Set up of Microsoft Teams webhooks to receive information from this solution.
- Deployment of a CloudFormation stack to the management account to configure the tag policy for this solution.
- Deployment of a CloudFormation stack set to member accounts to enable monitoring of S3 bucket tags and forwarding of tag compliance events to the security account.
- Deployment of a CloudFormation stack to the security account to configure the remainder of the solution that will facilitate sensitive data discovery, finding event processing, administrator notification, and release from quarantine functionality.
- Remaining manual configuration of quarantine remediation API authorization, enabling Macie, and specifying a Macie results location.
Set up Microsoft Teams
Before deploying the solution, you must create two incoming webhooks in a Microsoft Teams channel of your choice. Due to the sensitivity of the event information provided and the ability to release objects from quarantine, we recommend that this channel only be accessible to information security professionals. In addition, we recommend creating two distinct webhooks to distinguish tag compliance events from finding events and have named the webhooks in the examples S3-Tag-Compliance-Notification and Macie-Finding-Notification, respectively. A complete walkthrough of creating an incoming webhook is out of scope for this blog post, but you can access Microsoft’s documentation on creating incoming webhooks for an overview. After the webhooks have been created, save the URLs, to use in the solution deployment process.
Configure the management account
The first step of the deployment process is to deploy a CloudFormation stack in your management account that creates an AWS Organizations tag policy and applies it to the OUs of your choice. Before performing this step, note the two OU IDs you will apply the policy to, as these will be captured as input parameters for the CloudFormation stack.
- Choose the following Launch Stack button to open the CloudFormation console pre-loaded with the template for this step:

Note: The stack will launch in the N. Virginia (us-east-1) Region. To deploy this solution into other AWS Regions, change your regional selection in the CloudFormation console, and deploy it to the selected Region.
- For Stack name, enter ConfigureManagementAccount.
- For First AWS Organizations Unit ID, enter your first OU ID.
- For Second AWS Organizations Unit ID, enter your second OU ID.
- Choose Next.
Figure 3: Management account stack details


After you’ve entered all details, launch the stack and wait until the stack has reached CREATE_COMPLETE status before proceeding. The deployment process will take 1–2 minutes.
Configure the member accounts
The next step of the deployment process is to deploy a CloudFormation Stack, which will initiate a StackSet deployment from your management account that’s scoped to the OUs of your choice. This stack set will enable AWS Config along with an AWS Config rule to evaluate Amazon S3 tag compliance and will deploy an EventBridge rule to send compliance events from AWS Config in your member accounts to a centralized event bus in your security account. If AWS Config has previously been enabled, select True for the AWS Config Status parameter to help prevent an overwrite of your existing settings. Prior to performing this setup, note the two AWS Organizations OU IDs you will deploy the stack set to. You will also be prompted to enter the AWS account ID and Region of your security account.
- Choose the following Launch Stack button to open the CloudFormation console pre-loaded with the template for this step:
Note: The stack will launch in the N. Virginia (us-east-1) Region. To deploy this solution into other AWS Regions, change your regional selection in the CloudFormation console, and deploy it to the selected Region.
- For Stack name, enter DeployToMemberAccounts.
- For First AWS Organizations Unit ID, enter your first OU ID.
- For Second AWS Organizations Unit ID, enter your second OU ID.
- For Deployment Region, enter the Region you want to deploy the Stack set to.
- For AWS Config Status, accept the default value of false if you have not previously enabled AWS Config in your accounts.
- For Support all resource types, accept the default value of false.
- For Include global resource types, accept the default value of false.
- For List of resource types if not all supported, accept the default value of AWS::S3::Bucket.
- For Configuration delivery channel name, accept the default value of <Generated>.
- For Snapshot delivery frequency, accept the default value of 1 hour.
- For Security account ID, enter your security account ID.
- For Security account region, select the Region of your security account.
- Choose Next.

Figure 4: Member account Stack details

After you’ve entered all details, launch the stack and wait until the stack has reached CREATE_COMPLETE status before proceeding. The deployment process will take 3–5 minutes.
Configure the security account
The next step of the deployment process involves deploying a CloudFormation stack in your security account that creates all the resources needed for at-scale sensitive data detection, automated quarantine, and security professional notification and response. This stack configures the following:
- An S3 bucket and AWS Key Management Service (AWS KMS) keys for storage and encryption of discovery results in Macie.
- Two rules in EventBridge for routing tag compliance and Macie finding events.
- Two Step Functions state machines whose logic will be used for automated object quarantine and release.
- Three Lambda functions for tag compliance, Macie findings, and quarantine notification.
- A DynamoDB table for quarantine status tracking.
- An API Gateway REST endpoint to facilitate the release of objects from quarantine.
Before performing this setup, note your AWS Organizations ID and two Microsoft Teams webhook URLs previously configured.
- Choose the following Launch Stack button to open the CloudFormation console pre-loaded with the template for this step:
Note: The stack will launch in the N. Virginia (us-east-1) Region. To deploy this solution into other AWS Regions, change your regional selection in the CloudFormation console, and deploy it to the selected Region.
- For Stack name, enter ConfigureSecurityAccount.
- For AWS Org ID, enter your AWS Organizations ID.
- For Webhook URI for S3 tag compliance notifications, enter the first webhook URL you created in Microsoft Teams.
- For Webhook URI for Macie finding and quarantine notifications, enter the second webhook URL you created in Microsoft Teams.
- Choose Next.
Figure 5: Security account stack details

After you’ve entered all details, launch the stack and wait until the stack has reached CREATE_COMPLETE status before proceeding. The deployment process will take 3–5 minutes.
Remaining configuration
While most of the solution is deployed automatically using CloudFormation, there are a few items that you must configure manually.
Configure Lambda API key environment variable
When the CloudFormation stack was deployed to the security account, CloudFormation created a new REST API for security professionals to release objects from quarantine. This API was configured with an API key to be used for authorization, and you must retrieve the value of this API key and set it as an environment variable in your MacieQuarantineNotification function, which also deployed in the security account. To retrieve the value of this API key, navigate to the REST API created in the security account, select API Keys, and retrieve the value of APIKey1. Next, navigate to the MacieQuarantineNotification function in the Lambda console, and set the ReleaseObjectApiKey environment variable to the value of your API key.
Enable Macie
Next, you must enable Macie to facilitate sensitive data discovery in selected accounts in your organization, and this process begins with the selection of a delegated administrator account (that is, the security account), followed by onboarding the member accounts you want to test with. See Integrating and configuring an organization in Amazon Macie for detailed instructions on enabling Macie in your organization.
Configure the Macie results bucket and KMS key
Macie creates an analysis record for each Amazon S3 object that it analyzes. This includes objects where Macie has detected sensitive data as well as objects where sensitive data was not detected or that Macie could not analyze. The CloudFormation stack deployed in the security account created an S3 bucket and KMS key for this, and they are noted as MacieResultsS3BucketName and MacieResultsKmsKeyAlias in the CloudFormation stack output. Use these resources to configure the Macie results bucket and KMS key in the security account according to Storing and retaining sensitive data discovery results with Amazon Macie. Customization of the S3 bucket policy or KMS key policy has already been done for you as part of the ConfigureSecurityAccount CloudFormation template deployed earlier.
Validate the solution
With the solution fully deployed, you now need to deploy an S3 bucket with sample data to test the solution and review the findings.
Create a member account S3 bucket
In any of the member accounts onboarded into this solution as part of the Configure the member accounts step, deploy a new S3 bucket and the KMS key used to encrypt the bucket using the CloudFormation template that follows. Before performing this step, note the InvestigateMacieFindingsRole, StepFunctionsProcessFindingsRole, and StepFunctionsReleaseObjectRole outputs from the CloudFormation template deployed to the security account, as these will be captured as input parameters for the CloudFormation stack.
- Choose the following Launch Stack button to open the CloudFormation console pre-loaded with the template for this step:
Note: The stack will launch in the N. Virginia (us-east-1) Region. To deploy this solution into other AWS Regions, change your regional selection in the CloudFormation console, and deploy it to the selected Region.
- For Stack name, enter DeployS3BucketKmsKey.
- For IAM Role used by Step Functions to process Macie findings, enter the ARN that was provided to you as the StepFunctionsProcessFindingsRole output from the Configure security account step.
- For IAM Role used by Step Functions to release objects from quarantine, enter the ARN that was provided to you as the StepFunctionsReleaseObjectRole output from the Configure security account step.
- For IAM Role used by security professionals to investigate Macie findings, enter the ARN that was provided to you as the InvestigateMacieFindingsRole output from the Configure security account step.
- For Department name of the bucket owner, enter any department or team name you want to designate as having ownership responsibility over the S3 bucket.
- Choose Next.
Figure 6: Deploy S3 bucket and KMS key stack details

After you’ve entered all details, launch the stack and wait until the stack has reached CREATE_COMPLETE status before proceeding. The deployment process will take 3–5 minutes.
Monitor S3 bucket tag compliance
Shortly after the deployment of the new S3 bucket, you should see a message in your Microsoft Teams channel notifying you of the tag compliance status of the new bucket. This AWS Config rule is evaluated automatically any time an S3 resource event takes place, and the tag compliance event is sent to the centralized security account for notification purposes. While the notification shown in Figure 7 depicts a compliant S3 bucket, a bucket deployed without the required tags will be marked as NON_COMPLIANT, and security professionals can check the AWS Config compliance status directly in the AWS console for the member account.
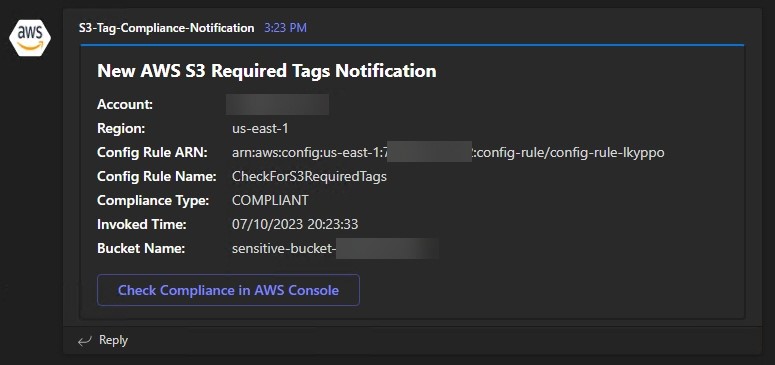
Figure 7: S3 tag compliance notification
Upload sample data
Download this .zip file of sample data and upload the expanded files into the newly created S3 bucket. The sample files include fictitious PII, including credit card information and social security numbers, and so will invoke various Macie findings.
Note: All data in this blog post has been artificially created by AWS for demonstration purposes and has not been collected from any individual person. Similarly, such data does not, nor is it intended, to relate back to any individual person.
Configure a Macie discovery job
Configure a sensitive data discovery job in the Amazon Macie delegated administrator account (that is, the security account) according to Creating a sensitive data discovery job. When creating the job, specify tag-based bucket criteria instructing Macie to scan any bucket with a tag key of RequireMacieScan and a tag value of True. This instructs Macie to scan buckets matching this criterion across the accounts that have been onboarded into Macie.
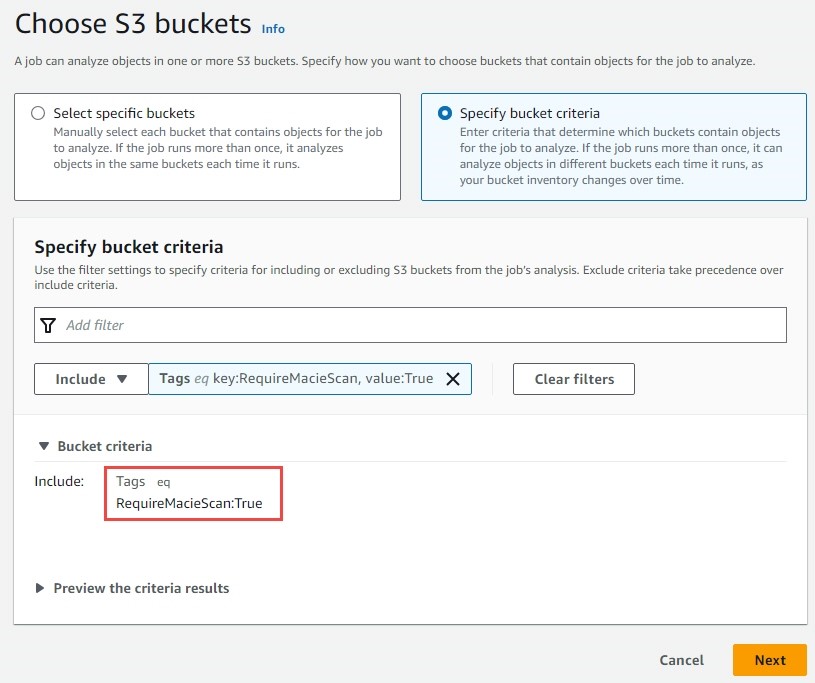
Figure 8: Macie bucket criteria
On the discovery options page, specify a one-time job with a sampling depth of 100 percent. Further refine the job scope by adding the quarantine prefix to the exclusion criteria of the sensitive data discovery job.
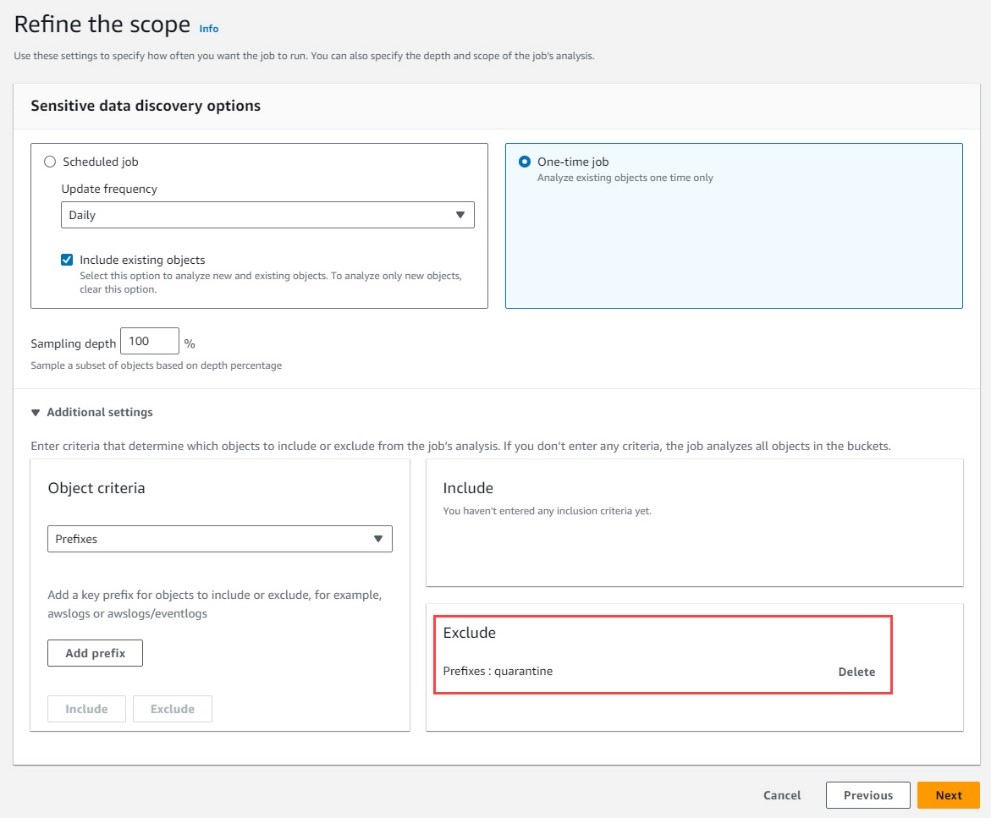
Figure 9: Macie scan scope
Select the AWS_CREDENTIALS, CREDIT_CARD_NUMBER, CREDIT_CARD_SECURITY_CODE, and DATE_OF_BIRTH managed data identifiers and proceed to the review screen. On the review screen, ensure that the bucket name you created is listed under bucket matches, and launch the discovery job.
Note: This solution also works with the Automated Sensitive Data Discovery feature in Amazon Macie. I recommend you investigate this feature further for broad visibility into where sensitive data might reside within your Amazon S3 data estate. Regardless of the method you choose, you will be able to integrate the appropriate notification and quarantine solution.
Review and investigate findings
After a few minutes, the discovery job will complete and soon you should see four messages in your Microsoft teams channel notifying you of the finding events created by Macie. One of these findings will be marked as medium severity, while the other three will be marked as high.
Review the medium severity finding, and recall the flow of event information from the solution overview section. Macie scanned a bucket in the member account and presented this finding in the Macie delegated administrator account. Macie then sent this finding event to EventBridge, which initiated a workflow run in Step Functions. Step Functions invoked customer-specified logic to evaluate the finding and determined that because the object isn’t publicly accessible, and because the finding isn’t high severity, it should only notify security professionals rather than quarantine the object in question. Several key pieces of information necessary for investigation are presented to the security team, along with a link to directly investigate the finding in the AWS console of the central security account.
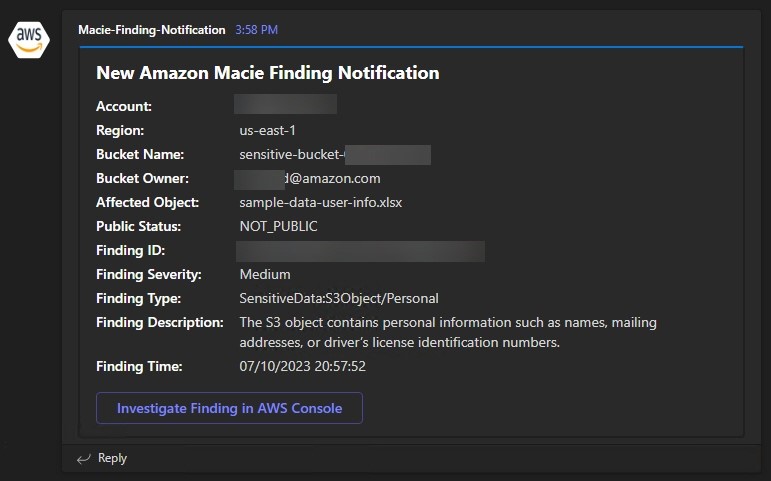
Figure 10: Macie medium severity finding notification
Now review the high severity finding. The flow of event information in this scenario is identical to the medium severity finding, but in this case, Step Functions quarantined the object because the severity is high. The security team is again presented with an option to use the console to investigate further. The process to investigate this finding is a bit different due to the object being moved to a quarantine prefix. If security professionals want to view the original object in its entirety, they would assume the InvestigateMacieFindingsRole in the security account, which has cross-account access to the S3 bucket quarantine prefix in the in-scope member accounts. S3 buckets deployed in member accounts using the CloudFormation template listed above will have a special bucket policy that denies access to the quarantine prefix for any role other than the InvestigateMacieFindingsRole, StepFunctionsProcessFindingsRole, and StepFunctionsReleaseObjectRole. This makes sure that objects are truly quarantined and inaccessible while being investigated by security professionals.
Figure 11: Macie high severity finding notification
Unlike the previous example, the security team is also notified that an affected object was moved to quarantine, and is presented with a separate option to release the object from quarantine. Choosing Release Object from Quarantine runs an HTTP POST to the REST API transparently in the background, and the API responds with a SUCCEEDED or FAILED message indicating the result of the operation.
Figure 12: Release object from quarantine
The state machine uses decision logic based on the affected object’s public status and the severity of the finding. Customers deploying this solution can choose to alter this logic or add additional customization by altering the Step Functions state machine definition either directly in the CloudFormation template or through the Step Functions Workflow Studio low-code interface available in the Step Functions console. For reference, the full event schema used by Macie can be found in the Eventbridge event schema for Macie findings.
The logic of the Step Functions state machine used to process Macie finding events follows and is shown in Figure 13.
- An EventBridge rule invokes the Step Functions state machine as Macie findings are received.
- Step Functions parses Macie event data to determine the finding severity.
- If the finding is high severity or determined to be public, the affected object is then added to the quarantine tracking database in DynamoDB.
- After adding the object to quarantine tracking, the object is copied into the quarantine prefix within its S3 bucket.
- After being copied, the object is deleted from its original S3 location.
- After the object is deleted, the MacieQuarantineNotification function is invoked to alert you of the finding and quarantine status.
- If the finding is not high severity and not determined to be public, the MacieFindingNotification function is invoked to alert you of the finding.
Figure 13: Process Macie findings workflow

Solution cleanup
To remove the solution and avoid incurring additional charges for the AWS resources used in this solution, perform the following steps.
Note: If you want to only suspend Macie, which will preserve your settings, resources, and findings, see Suspending or disabling Amazon Macie.
- Open the Macie console in your security account. Under Settings, choose Accounts. Select the checkboxes next to the member accounts onboarded previously, select the Actions dropdown, and select Disassociate Account. When that has completed, select the same accounts again, and choose Delete.
- Open the Macie console in your management account. Click on Get started, and remove your security account as the Macie delegated administrator.
- Open the Macie console in your security account, choose Settings, then choose Disable Macie.
- Open the S3 console in your security account. Remove all objects from the Macie results S3 bucket.
- Open the CloudFormation console in your security account. Select the ConfigureSecurityAccount stack and choose Delete.
- Open the Macie console in your member accounts. Under Settings, choose Disable Macie.
- Open the Amazon S3 console in your member accounts. Remove all sample data objects from the S3 bucket.
- Open the CloudFormation console in your member accounts. Select the DeployS3BucketKmsKey stack and choose Delete.
- Open the CloudFormation console in your management account. Select the DeployToMemberAccounts stack and choose Delete.
- Still in the CloudFormation console in your management account, select the ConfigureManagementAccount stack and choose Delete.
Summary
In this blog post, we demonstrated a solution to process—and act upon—sensitive data discovery findings surfaced by Macie through the incorporation of decision logic implemented in Step Functions. This logic provides granularity on quarantine decisions and extensibility you can use to customize automated finding response to suit your business and regulatory needs.
In addition, we demonstrated a mechanism to notify you of finding event information as it’s discovered, while providing you with the contextual details necessary for investigative purposes. Additional customization of the information presented in Microsoft Teams can be accomplished through parsing of the event payload. You can also customize the Lambda functions to interface with Slack, as demonstrated in this sample solution for Macie.
Finally, we demonstrated a solution that can operate at-scale, and will automatically be deployed to new member accounts in your organization. By using an in-place quarantine strategy instead of one that is centralized, you can more easily manage this solution across potentially hundreds of AWS accounts and thousands of S3 buckets. By incorporating a global tracking database in DynamoDB, this solution can also be enhanced through a visual dashboard depicting quarantine insights.
If you have feedback about this post, let us know in the comments section. If you have questions about this post, start a new thread on AWS Security, Identity, & Compliance re:Post or contact AWS Support.
Want more AWS Security news? Follow us on Twitter.