Give every teammate and agent the right level of access to your Workers

Post Syndicated from Dina Kozlov original https://blog.cloudflare.com/workers-granular-authorization/

As more teams — and now agents — build applications on Cloudflare's Developer Platform, having the right access controls is crucial to allow you to ship safely. After all, the last thing you want is for an agent to make a change in production, just because it was granted more access than it needs.

Now, you can give a teammate or agent access to a specific Worker, so that they can only make changes to that application and no other resources in your account. Moreover, we’re giving you four new roles, so you can limit exactly what they can do: 

The new roles are available today, for all customers. You can assign them to a specific user, so when they log into the dashboard, they will only see the Worker you have given them access to. Or, you can create an API token with the scoped access, which you can give to your agent to ensure they only have access to that one application. 

Here’s an example of how to create an API token with permissions per Worker: 

Roles designed for how teams build

When defining these roles, we wanted to strike the right balance. Overly broad roles force you to grant more access than intended, undermining the principle of least privilege, while providing too many individual permissions makes it difficult to know which ones to grant. We landed on four roles that reflect the levels of access you may want to give a person or agent: enough to debug a resource without exposing its content, read the content without changing it, make changes without being able to delete the resource, or fully manage it.

We plan to use these same roles as we bring resource-level access controls to other Developer Platform products, including D1, R2, and KV. Each role can be applied at one of three scopes. For example, if you set the “metadata read-only” control, here’s what that would look like at different levels: 

  • Developer Platform level: Access to metadata for all Developer Platform resources.
  • Product level: Access to metadata for every resource of one product, such as every Worker.
  • Resource level: Access to metadata for one specific resource, such as one Worker.

The role and scope determine what someone can do and which resources they can do it to. Let’s take a look at how this would look in some common Workers workflows.

Debug without exposing source code

To debug an issue, an engineer or agent might need to look at a Worker’s settings, metrics, logs, and traces to understand what went wrong. But they do not need to see the Worker’s code or make changes to it.

Metadata Read-Only gives them access to that information without exposing the Worker’s source code. They can query analytics through the GraphQL API, access logs, and inspect traces and other observability data. Those requests only return data for the Workers they have access to. If an agent is scoped to one Worker, it can use the Cloudflare APIs to investigate an issue without seeing data from any other Worker in the account.

As we bring these roles to more Developer Platform products, we plan to preserve that separation. Someone could inspect settings and observability data for a D1 database or R2 bucket without being able to read the values in the database or the files in the bucket.

Review code without changing it 

A teammate or code review agent may need to read the code running in a Worker to understand how it works, investigate a bug, or review a proposed change. But that does not mean they should be able to deploy new code or update the Worker’s settings.

Content Read-Only provides that separation. It lets them retrieve and review the Worker’s code without being able to modify or deploy it. When scoped to an individual Worker, they can read only that Worker’s code, rather than the code for every Worker in the account.

Once supported for other Developer Platform products, Content Read-Only will work the same way: someone could read the data stored in a D1 database, KV namespace, or R2 bucket without being able to modify it.

Let CI deploy without giving it full control

A CI/CD workflow only needs access to the application it deploys. It should not be able to change another Worker or delete its own and take the application offline.

With Worker-level access controls, each workflow can have its own API token with the Editor role, scoped to one Worker. If the workflow is misconfigured or its token is exposed, the impact remains contained: it can deploy changes to that Worker, but it cannot delete it or touch any other application in your account.

Delete a Worker with Admin access

Admin is the highest level of access you can grant. It allows you to delete an application. You can still scope the role to an individual Worker, so that access does not extend to every Worker in the account.

Routes & Custom Domains 

You can add routes or Custom Domains to a Worker to specify which hostnames are routed to that application. For example, this configuration in your Wrangler file sends traffic for example.com to the Worker:

Because changing that route could redirect production traffic or take the application offline, access to the Worker alone is not enough. To add, change, or remove a route or Custom Domain, you need both Editor access to the Worker and Workers Routes permission for the zone.

Requiring Workers Routes permission, rather than broader access to the zone, means someone can manage how traffic reaches a Worker without being able to change unrelated settings for the domain.

However, once a route is configured, you can continue deploying new versions of the Worker without access to the connected zone or resource, as long as the deployment does not change that connection. This allows your CI/CD system to deploy the application without also giving it access to your domains, databases, or storage.

Workers permissions extend to Durable Objects

Durable Objects do not have their own roles or permissions. Instead, access to a Durable Object is determined by your access to the Worker that implements it. To give someone access to a Durable Object, grant them the appropriate role for that Worker.

Metadata Read-Only gives them access to Durable Object metrics, logs, and traces, but not the data stored in the object. Because Durable Objects Data Studio can query and modify that stored data directly, accessing it requires the Editor role.

Better errors that tell you and your agents which permissions you need

When you give someone narrowly scoped permissions, they may eventually try to perform an operation they do not have access to. When that happens, the error should tell them what permission they need, so they don’t get stuck.

Instead of returning only a generic 403 Forbidden response, our APIs now include a link to the relevant API documentation, where you can see exactly which permissions are required to make the request. This way, you and your agent can figure out exactly the right level of access that’s needed without granting broader permissions than necessary.

Available now

Worker-level access controls are available today for all customers. You can configure them in the Cloudflare dashboard, through the API, or with Terraform.

To give a team member access to a specific Worker, go to Manage Account > Members, select the member, and create a policy with the role and Worker scope they need.

Manage team access with user groups

If several people on the same team or project need the same access, you can create a User Group instead of assigning permissions to each person individually. Assign the policy to the group, then add the relevant members. Everyone in that group will automatically inherit that policy.

Replacing legacy permissions for Workers 

Previously, we used the following roles and permissions to manage access to Workers. Now that we are rolling out a consistent set of roles across the Developer Platform, we recommend using the new roles going forward.

There is no deprecation date for the legacy roles and permissions. Existing assignments will continue to work, and we will provide advance notice before any deprecation. That said, we recommend starting to move to the new roles, since they're the ones that support granular, resource-level access. 

What’s next? 

Worker-level access is the first step toward a more consistent authorization model across Cloudflare's Developer Platform.

Next, we are bringing the same resource-level access controls to more Developer Platform products, including resources like KV namespaces and D1 databases. Instead of granting someone access to every bucket or every database in an account, you will be able to scope access to the specific resource they need and pair that scope with the right role.

The same roles introduced for Workers will apply across these resources.

Check out our developer docs to get started.
Bring AI literacy into every classroom with our new themed resources

Post Syndicated from Emma Staves original https://www.raspberrypi.org/blog/bring-ai-literacy-into-every-classroom-with-our-new-themed-resources/

Artificial intelligence (AI) is already part of young people’s everyday lives, from the content recommended to them on social media to the generative AI tools they increasingly encounter. But AI technologies are also being used to tackle challenges in the wider world, from forecasting floods to monitoring our environment.

That’s why we believe AI literacy shouldn’t sit within a single subject. Young people need opportunities to explore how AI works, where it is used, and the questions it raises across the curriculum.

To address this, we created a new collection of free themed Experience AI resources, designed to make it easier for educators to bring AI literacy into the subjects and topics they already teach. The resources include those co-developed by the Raspberry Pi Foundation and Google DeepMind, alongside those developed independently by the Raspberry Pi Foundation, including two units created with support from our partner, Digital Moment.

Explore AI through the issues that matter

When we began developing these resources, we initially explored creating materials specifically for individual curriculum subjects. But through conversations with educators and our partners around the world, we learnt that a more flexible approach could be much more useful.

Curricula differ between countries, schools, and age groups, and AI technologies rarely fit neatly within traditional subject boundaries. The same technology can raise scientific, geographical, social, creative, and ethical questions.

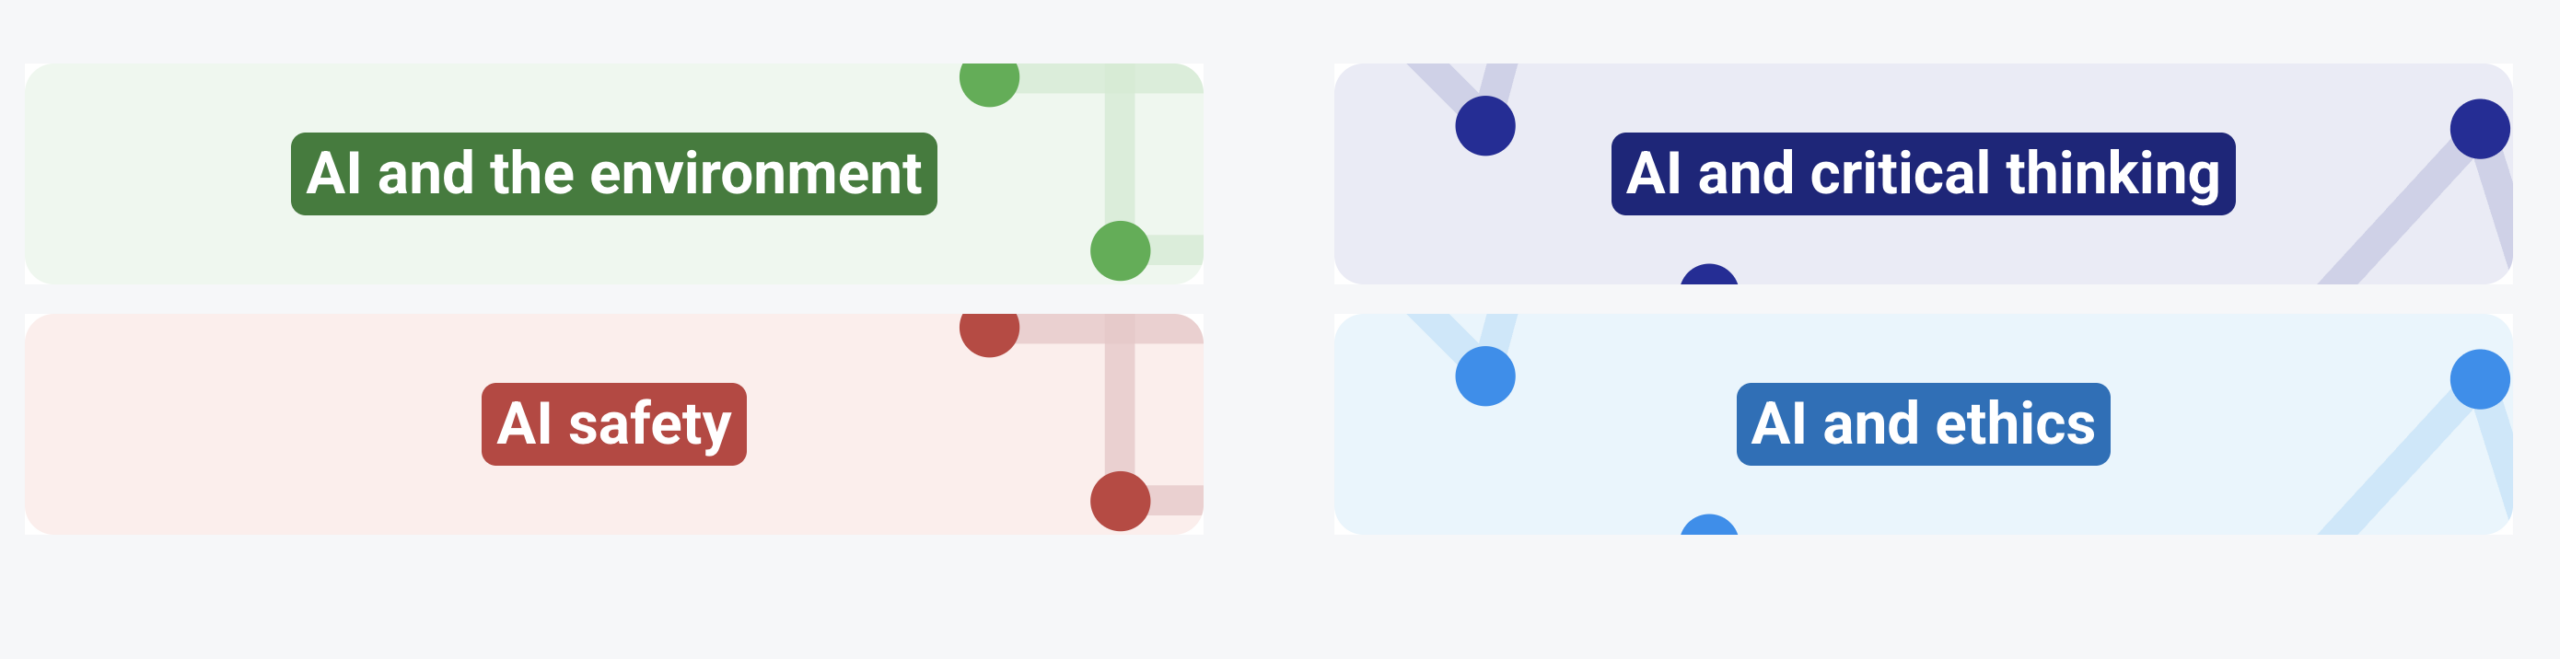
So rather than assigning each resource to a particular subject, our new resources are organised around broad themes, including the environment, critical thinking, and ethics.

The themes of resources:

The environment, critical thinking, and ethics.

The resources include:

  • Flood forecasting, a lesson that explores how AI tools can be used to predict flooding
  • AI and social media, a unit that helps young people investigate how their online behaviour influences the content they are shown
  • AI detectives: The case of the clever claim, an activity that develops critical thinking about AI tools and the claims made about them

Designed for learners aged 8 to 16, the resources can be used in different subjects and adapted by educators to suit their own classroom context.

That flexibility is important. We want educators to be able to introduce meaningful AI literacy without feeling that they need to become AI specialists or find space for an entirely new subject in an already busy curriculum.

AI literacy across the curriculum

The need for this approach is increasingly recognised by subject experts.

Dr Becky Kitchen, Head of Professional Development at the Geographical Association, highlighted the importance of giving young people opportunities to engage critically with AI technologies as part of their wider learning:

Dr Becky Kitchen, Head of Professional Development at the Geographical Association

“Pupils are increasingly coming into contact with AI and so it’s vital that they are taught how to harness its power in an effective and critical way. Developing resources across the curriculum to embed this knowledge, understanding, and use is critical.”

After reviewing the new resources, she added:

“These resources are outstanding. They develop pupils’ geographical knowledge while simultaneously exploring the role that AI can have in a meaningful and concrete way.”

The connections extend well beyond geography.

Professor Geoff Cox, Professor of Art and Computational Culture at London South Bank University, emphasised the role that arts and humanities subjects can play in developing a richer understanding of AI technologies:

“If AI literacy is left solely to STEM subjects or computer science, we lose the opportunity to ask deeper human, cultural, and ethical questions — questions that art is uniquely equipped to explore.”

He also highlighted the value of combining different ways of learning:

“The resources move between visual analysis, practical activity, and critical reflection, recognising that only in combination can AI literacy be developed effectively.”

These perspectives reflect an important principle behind the collection. AI literacy isn’t simply about knowing how a technology works. It is also about being able to question it, understand its applications and limitations, and consider its impact on people, communities, and the world.

Tested in real classrooms

Before launching the resources more widely, earlier this year we collaborated with our partner, Digital Moment, to give educators in Canada the opportunity to test some of them with their students. Their experiences helped us understand not only how the resources worked in practice, but also where they could fit naturally into existing teaching.

As Indra Kubicek, CEO of Digital Moment, explains:

“Educators play a critical role in helping students understand and think critically about the use of AI and its implications across a wide range of subjects. Building the next generation of creators, builders, and innovators who will shape the future of AI starts with AI education in the classroom.”

One of the educators who took part was Grade 8 teacher Sandra Theobald, who tested our AI and social media activity. Before the lesson, she expected her students, who were already regular social media users, to be familiar with many of the ideas.

Grade 8 teacher Sandra Theobald

While they did have a good background knowledge, the activity prompted them to make new connections between their own behaviour, the data they generate, and the content they are shown as a result of the algorithms presented to them.

Students were able to explore the ideas themselves, with Sandra taking more of a supporting role. She found that they came away feeling more confident about understanding how their interactions with social media affect what they see, and keen to share what they had discovered with their families.

For educators who may feel unsure about introducing AI tools in their classroom, Sandra’s advice is to simply give it a go, rather than waiting until feeling like an expert:

“My advice is to start small and seek out trusted resources and experts in AI education. Partner with another educator so you can explore and learn together. There is so much information available that it can feel overwhelming, so take it one step at a time. Learn alongside your students and build your confidence as you go.”

A powerful and easy resource for teachers

Canadian educator Colin McKenzie also used the AI and social media unit with his Grade 7 and 8 classes.

Canadian educator Colin McKenzie

Using Somekone, a closed social media simulation for the classroom, his students created accounts and explored how their behaviour affected the content the system recommended.

The experience felt familiar enough to capture their attention, but gave them an opportunity they wouldn’t normally have when using a real social media platform: to examine what was happening behind the scenes.

Students reflected on their interests and choices and then used data on their own behaviour to understand how that behaviour affected what they were shown. Colin found that students were eager to return to the activity each day to discover what would happen next.

Crucially, he also found it straightforward to incorporate the activity into his existing teaching rather than having to significantly change his plans.

“I think this is a powerful and easy resource for teachers to use in the classroom. It is easy to set up and navigate, and it ties in well with curriculum areas around online usage, especially with how prominent AI is becoming in our educational lives.”

For Colin, the activity provided a practical way to connect AI literacy with what his students had already learnt about online safety and evaluating information. It also helped students recognise that the content they encounter online isn’t simply appearing by chance: their own actions can influence the content recommended to them by AI-driven systems.

The experience was valuable enough that Colin plans to make the unit part of his teaching each year.

Giving educators flexibility

Feedback like this has reinforced why flexibility is central to our approach.

A lesson about flood forecasting might support learning in geography or science. Exploring AI-generated content could lead to discussions in art, media literacy, humanities, or computing. An activity investigating social media algorithms can connect AI literacy with online safety, critical thinking, and digital citizenship.

Young learners in the classroom using Experience AI resources in Malaysia

Most importantly, these things provide opportunities for students to encounter AI literacy in different contexts and recognise that understanding AI is relevant far beyond the computing classroom.

AI literacy belongs in every classroom

AI technologies will continue to change. The contexts in which young people encounter them will change too.

Our aim isn’t to prepare students for one particular AI tool or moment in time. It’s to help them develop the knowledge and critical thinking skills they need to understand all kinds of AI technologies, question them, and make informed decisions about them.

Educators shouldn’t need to be computer science teachers, or AI experts, to do that.

By creating flexible resources that connect AI with subjects and issues young people are already exploring, we hope to make it easier for more educators to bring AI literacy into their classrooms.

Explore the new themed Experience AI resources and discover a starting point for your learners.

We’d like to say a big thank you to our global partner, Digital Moment, for their support in trialling these new resources with educators and learners in Canada.

The post Bring AI literacy into every classroom with our new themed resources appeared first on Raspberry Pi Foundation.

CVE-2026-76461: Critical Cisco Secure Email Gateway Vulnerability Exploited in the Wild

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/etr-cve-2026-76461-critical-cisco-secure-email-gateway-vulnerability-exploited-in-the-wild

Overview

On September 14, 2026, Cisco published a security advisory for CVE-2026-76461, a critical SQL injection vulnerability affecting Cisco AsyncOS Software for Cisco Secure Email Gateway. The vulnerability has a reported CVSS v3.1 base score of 9.8 and could allow an unauthenticated, remote attacker to execute arbitrary commands with root privileges on an affected appliance.

Cisco Secure Email Gateway, formerly known as IronPort Email Security Appliance, is an enterprise email security product that inspects inbound and outbound email for threats including phishing, malware, spam, and business email compromise. Because affected gateways process externally delivered email as part of their normal operation, exploitation does not require access to an administrative interface or authentication. An attacker can reportedly trigger the vulnerability by sending a specially crafted email through a vulnerable gateway.

CVE-2026-76461 was added to CISA’s Known Exploited Vulnerabilities (KEV) catalog on the same day as the vendor disclosed the vulnerability, indicating that CVE-2026-76461 was exploited as a zero-day prior to disclosure. Cisco noted that their PSIRT became aware of active exploitation in September 2026. At the time of publication, there is no public proof-of-concept exploit code available, and no attribution for the current threat actor activity.

Mitigation guidance

Organizations running Cisco Secure Email Gateway should prioritize upgrading to a vendor-supplied fixed version on an emergency basis, outside of normal patching cycles.

Affected Version

Fixed Version

15.5 and earlier

15.5.5-014

16.0

16.0.4-302

16.5

16.5.0-780

Given the reported active exploitation and the ability to achieve unauthenticated root-level command execution through malicious email processing, organizations should prioritize patching rather than relying solely on network controls or monitoring. Cisco also strongly recommends that customers migrate to the latest product version, 16.5.0-780.

For the latest remediation guidance, see the vendor advisory.

Indicators of compromise

The following indicators of compromise for CVE-2026-76461 were reported within the Cisco security advisory.

To confirm any attempted exploitation of this vulnerability, review the mail_logs and look for suspicious SQL statements. If the device is part of a cluster, review the logs of each cluster device. The following is a non-exhaustive example of how a malicious SQL statement could be detected in the logs:

cisco-esa> grep -i “COPY.*TO PROGRAM” [IronPort Text Mail Logs Log name – Default: mail_logs]

The presence of any entry in the output may indicate malicious activity.

Rapid7 customers

Exposure Command, InsightVM, and Nexpose

Exposure Command, InsightVM, and Nexpose customers can assess exposure to CVE-2026-76461 with a vulnerability check expected to be available in the September 16 content release.

Updates

  • September 15, 2026: Initial publication.

25 Years of Mass Surveillance Is Enough

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/25-years-of-mass-surveillance-is-enough.html

This essay was written with Cindy Cohn, and originally appeared in Lawfare.

One of the many legacies of the terrorist attacks of Sept. 11 is the government-wide shift from targeted surveillance—such as individual wiretaps or pen register/trap and trace orders—to mass surveillance techniques—such as tapping into the internet backbone or mass collection of telephone or internet metadata. The legal and technical architecture of modern mass surveillance, initially framed as a necessary defense against terrorist threats, has grown far beyond that justification and national security in general. Mass surveillance is now a routine tool used by law enforcement. ICE uses it in immigration actions and against people exercising their First Amendment rights to protest. It’s also increasingly part of private security systems, such as facial recognition at venues such as Madison Square Garden and networked Flock license plate capture systems on roads and in parking lots.

The interrelation between private and governmental mass surveillance is worth examining. Surveillance is the business model of the internet; companies like Google and Facebook constantly spy on their users’ behavior. From the National Security Agency relying on data collected by telecommunication and internet companies, to local sheriffs and ICE agents relying on cellphone location data and privately managed automatic license plate readers, governments primarily obtain the mass surveillance information through private companies. Increasingly, access doesn’t just come through legal processes, either. FBI Director Kash Patel recently confirmed in congressional testimony that the agency is purchasing information on Americans from data brokers and intends to continue to do so.

This pipeline from private collection to governmental collection means that as companies collect more information for surveillance capitalism purposes, more is available to law enforcement as well. And as the technology for mass surveillance and analysis improves, especially with the increased use of AI technologies, the problems attendant to mass surveillance grow as well.

After 9/11, the idea that the government could surveil the population to safety took hold. In 2001, the fear of terrorism reached a frequency and intensity never before seen. Along with that came the fear that the enemy could be anyone, anywhere. As a result, the government’s response was to watch everyone, everywhere. This line of reasoning underpinned the shift from targeted to mass surveillance. Or, in the words of an internal National Security Agency (NSA) presentation that was made public as part of Edward Snowden’s 2013 disclosures, a government that can “Collect it All,” “Process it All,” “Exploit it All,” “Partner it All,” and “Sniff it All,” will ultimately, “Know it All.” Similar rationales support the rise of domestic mass surveillance: if law enforcement could see and hear everything, it could more effectively interdict and solve serious crimes.

The national security community has never provided a full analysis of the costs and benefits of these mass surveillance programs, either in terms of taxpayer dollars or diversion of resources from other efforts—or any demonstration that those techniques stopped attacks that otherwise they would not have been able to prevent. While the NSA occasionally presents examples of the successes due to its mass surveillance programs, especially when those techniques are under public pressure, the examples also regularly fall apart upon serious scrutiny. And even if some utility exists, it must be seriously weighed against the costs.

Similarly, there has never been any comprehensive analysis about whether domestic immigration or law enforcement’s use of these techniques actually makes people safer, or whether other techniques could produce the same results. Instead, both the police and the companies selling these tools float anecdotes and dubious data. For example, Flock’s data equates the number of law enforcement hits in their database with actually solving crimes.

Twenty-five years after 9/11, it seems reasonable to step back and evaluate the costs of this shift to mass surveillance, especially in terms of Americans’ rights and freedoms.

The Shift

The easiest place to see a shift to mass surveillance was in the government’s decision immediately after 9/11 to collect Americans’ telephone records. The program started under an argument of pure executive power as the “President’s Surveillance Program.” But in 2006, that argument secretly shifted to a novel interpretation of Section 215 of the Patriot. Act which had only previously authorized more targeted access to record. While some media and public interest organizations struggled to force the government to reveal the program as early as late 2005, the government only officially confirmed it after the 2013 Snowden disclosures. In 2015, the Second Circuit Court of Appeals rejected the government’s interpretation of Section 215 as allowing mass collection of telephone records. Later the same year, Congress passed the USA Freedom Act. While this new law still allows collection of a tremendous amount of domestic telephone records, it ended the indiscriminate mass collection that had occurred for nearly fourteen years.

Other shifts to mass surveillance continue through today. The NSA launched its Upstream program, which involved intercepting both metadata and content from key telecommunications junctures inside the U.S., soon after 9/11. It was also initially conducted under a claim of purely presidential authority. This program was brought under marginal congressional and programmatic (not targeted) Foreign Intelligence Surveillance Act (FISA) court review via Section 702 of the 2008 FISA Amendments Act. In 2017, more than15 years after its inception, the NSA ended content searches due to FISA court pressure, but the mass collection continues.

Despite the stated goal of conducting mass spying only on people outside the U.S.—which itself is problematic given international law’s requirement that surveillance be both necessary and proportionate—mass surveillance collects a tremendous amount of U.S. persons’ communications. This can happen because people communicate with people abroad, or because of overcollection—when government agencies gather far more personal data on non-targeted US persons than authorized by law. The concerns about collecting Americans’ data on U.S. soil led Congress to allow the program to officially expire in 2026, although the previously-approved mass surveillance itself continues until at least Spring of 2027.

The shift to mass surveillance would be notable enough even if it remained only a strategy of the intelligence community. It has not. Americans are awash in mass surveillance. Networks of automated license plate readers such as those offered by Flock and Vigilant Solutions blanket both public and private roadways and parking lots. These networks often allow searches by law enforcement, including across jurisdictions. They are, for example, being used to track people seeking abortions across state lines. Facial recognition tools, once the province of only the more elite parts of federal law enforcement, are increasingly used by Immigration and Customs Enforcement agents on immigrants and protesters, in airports by the Transportation Security Administration, as well as by private entities. And, of course, modern phones track users’ locations constantly—and that information is readily available to law enforcement, often with only minimal process protections.

Constitutional Costs

Regardless of the murkiness of its actual usefulness, the shift from targeted to mass surveillance has profound implications for Americans’rights. It has created risks that have become increasingly evident, especially under the Trump administration.

At a basic level, the Fourth Amendment guarantees that citizens can be secure in their “persons, houses, papers and effects” from unreasonable searches. Warrants breaching that security should be supported by probable cause and particular descriptions of the place to be searched and items to be seized. Mass surveillance turns that promise on its head, allowing access to our “papers and effects” by the government without individualized suspicion or a particularized description of what data is being seized, much less probable cause. This protection was in response to colonial British misuse of writs of assistance, which authorized indiscriminate searches rather than targeted ones.

The justifications for exempting mass surveillance from constitutional protection vary. For Section 702, the government has taken the position that U.S. persons’ communications caught up in the dragnet, either due to overcollection or because they were communicating with someone outside the United States, do not require a warrant prior to initial collection or secondary access by the FBI and several other agencies. The argument is that if the initial collection was not aimed at Americans, the information is free from constitutional protection for any later uses, even for reasons far afield from the initial rationale for collection.

Other arguments rest on the claim that metadata is outside the Fourth Amendment, despite its demonstrated ability to reveal intimate details of all of our lives. Still others rest on the Supreme Court-created Third Party Doctrine, which holds that the Fourth Amendment does not apply to data shared with companies that provide us with services. Some turn on whether analysis by machine counts, claiming that only “human eyes” matter—a particularly troubling argument with the rise of artificial intelligence. What’s more, the government has used doctrines like standing to limit the ability of those subjected to mass surveillance to seek constitutional protection. No matter the argument, the goal is the same: to place the mechanisms and fruits of mass surveillance outside the protections of the Fourth Amendment.

The overarching truth is that, due to the concerted efforts by the government since 9/11, and the rise of technologies in recent years, the slice of Americans’ lives and data that are actually protected by the Fourth Amendment has shrunk significantly in the past 25 years. Together, with the technical capabilities of mass surveillance and the increased ability for that data to be analyzed using AI tools, the “security in our papers and effects” that the constitution promises seems increasingly illusory.

In addition to the Fourth Amendment, mass surveillance creates tensions with the First Amendment. The Constitution has long recognized that the right to freedom of speech requires a zone of privacy against governmental surveillance. The right to anonymous speech as well as the right of association both recognize the chilling effect that surveillance creates for people saying unpopular things or attempting to organize for political or other societal change. Mass surveillance grants the authorities the ability to track those people, both in real time and historically, that is inconsistent with actual techniques of freedom of speech and assembly.

That is why the recently released 2026 U.S. Counterterrorism Strategy is so troubling. On page seven, the White House expressly states that it intends to target domestic activists with its heretofore foreign-targeted powers. It says that the government “will prioritize the rapid identification and neutralization of violent secular political groups whose ideology is anti-American, radically pro-transgender and anarchist” and “will use all the tools constitutionally available to us to map them at home, identify their membership, map their ties to international organizations like Antifa.” While framed as targeting “violent” groups, it’s clear that the government intends to use its national security tools, presumably including the tools of mass surveillance, against Americans in ways that will create profound tensions with the First Amendment rights of people to organize and communicate privately.

Costs Due to Mistakes and Abuse

Even assuming some utility from mass surveillance—a fact we do not dispute, even if the public record is shaky and conclusory—the history of both the national security and domestic uses of mass surveillance confirms that these tools are inevitably misused, and that mistakes have impacted huge numbers of Americans. The past twenty-five years have demonstrated that it is not possible to surveil the entire US population while staying within the bounds of even a very generous legal framework like Section 702.

As Rep. Zoe Lofgren (D-Calif.) recently stated in discussion of Section 702 in an interview with Tech Policy Press: “backdoor searches have been used improperly for protestors, 19,000 campaign donors, members of Congress, journalists, government officials, a state court judge who had complained to the FBI about police misconduct. It has been abused substantially in the past.” The NSA experienced so much abuse of its mass surveillance tools by actual or aspiring romantic partners and ex-spouses that an internal name emerged for it: “LOVEINT,” or Love Intelligence.

That same pattern of abuse is now emerging at the domestic law enforcement level. A Texas police officer misused, and then lied about, using license plate readers to track a woman suspected of seeking an abortion. Multiple law enforcement officials have been accused of tracking people they either wished to have a relationship with or who were their exes. And mass surveillance technologies have been used to track both immigration targets and citizens engaging in their First Amendment-protected right to track and record the police.

Mistakes are inevitable with collections of data of this size and scope. The history of the FISA court’s reviews of Section 702 is littered with examples of the NSA not being able to follow its own rules limiting the scope of what it collects and analyzes, even after having been given multiple chances by the court. On the local level, the technical protections that Flock, for example, put in place have repeatedly been insufficient to stop “accidental” sharing its data with out-of-state law enforcement. These mistakes have fueled growing efforts by local communities across the country to remove license plate readers. Those efforts should be the first step in a broader reconsideration of mass surveillance.

More generally, ubiquitous surveillance carries a real societal cost. The chilling effects are real and pervasive, and they tend to fall hardest on the most marginalized members of society. Moreover, social progress requires the ability to experiment in secret. It’s hard to imagine a society progressing morally to the point of accepting and legalizing things like marijuana use or gay marriage if the earliest signs of that shift are snuffed out because of overzealous surveillance.

Reversing Course

While a cost-benefit analysis is not the best frame for deciding constitutional rights, it is a place to start to evaluate government policies. If the costs are too high and the benefits too small, what should the public do? While the policy and legal frameworks can be individually complex, mass surveillance is a problem in all of its applications. So too should solutions be comprehensive rather than piecemeal.

One comprehensive strategy is to reset the promise of the Fourth Amendment and recognize that a warrant is required prior to collection, access or use of information gathered through mass surveillance. This would apply to collections that include U.S. persons, whether done for national security or domestic purposes. This protection would apply regardless of whether the information is in the form of metadata. It would apply regardless of whether the information is held in homes or by services people rely on, such as telephones, internet or social network providers, or by private entities utilizing mass surveillance for their own purposes. By passing this legislation, Congress could ensure this rejection of mass surveillance, and include real enforcement such as a private right of action and an automatic exclusionary remedy in criminal prosecutions. The courts could also recognize this protection of “papers and effects” directly as a plain language interpretation of the Fourth Amendment.

There are already a number of efforts that take on pieces of mass surveillance. Section 702 has expired and should remain so. This was due largely to efforts to block the “back door” access to Section 702-collected data without warrants. The bipartisan “Fourth Amendment is Not for Sale Act” would prevent the government from purchasing data that it would otherwise need a warrant to obtain. The Supreme Court itself has already been chipping away at the Third Party Doctrine, with a recent step in the rejection of mass geofence warrants—warrants seeking the identities of individuals based upon their proximity to a crime—in Chatrie v. United States. Now, such warrants fall, at least initially, under the Fourth Amendment.

A more comprehensive approach would also address mass surveillance carried out by private companies, and to ensure that Americans have the right to encrypt and secure their data. There are many reasons the United States would benefit from a comprehensive privacy law—and curbing mass surveillance is one of them. Addressing mass surveillance is certainly one of them. Ideas such as the banning of secondary uses of data—with roots in the Fair Information Practice Principles from the 1970s—are worth pushing forward. So are moves such as creating fiduciary duties for mass data collectors. There are many more ways to curtail private companies’ mass surveillance while staying within constitutional boundaries. But addressing the costs of mass surveillance by both companies and governments is even more important in a world where AI agents are making decisions both about the public and on their behalf based on their data and observed behavior.

Twenty-five years after the U.S. government embraced mass surveillance, it’s time to evaluate it as a whole, and consider responses that address the problem as a whole. Americans must ask: Is it consistent with a self-governing democracy to have systems that watch everyone everywhere? Is the public comfortable with governments—federal, state, local—that seek to “know it all” about its citizens? Is the public comfortable with private mass surveillance in its own right and as it’s being increasingly used to fuel government surveillance? These questions have long needed serious consideration. But as it becomes increasingly evident that the Trump administration is using mass surveillance to keep itself in power, stifle dissent, and undermine political opponents, these questions are now more urgent than ever.

Президентски избори 2026 – напредък на заявленията

Post Syndicated from Боян Юруков original https://yurukov.net/blog/2026/pr206-napredak/

Измина седмица откакто ЦИК пусна формуляра за заявленията за гласуване зад граница. Писах подробно за него и защо е важен. Чести проблеми и грешки при попълването ще намерите в статията ми от март т.г.

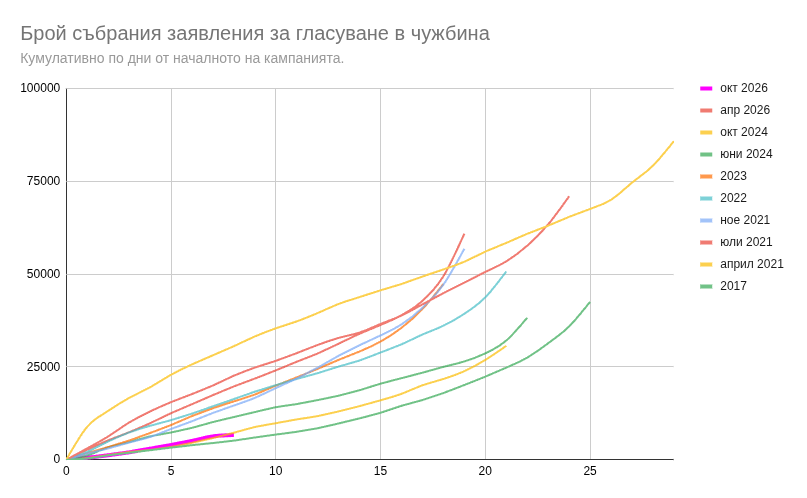
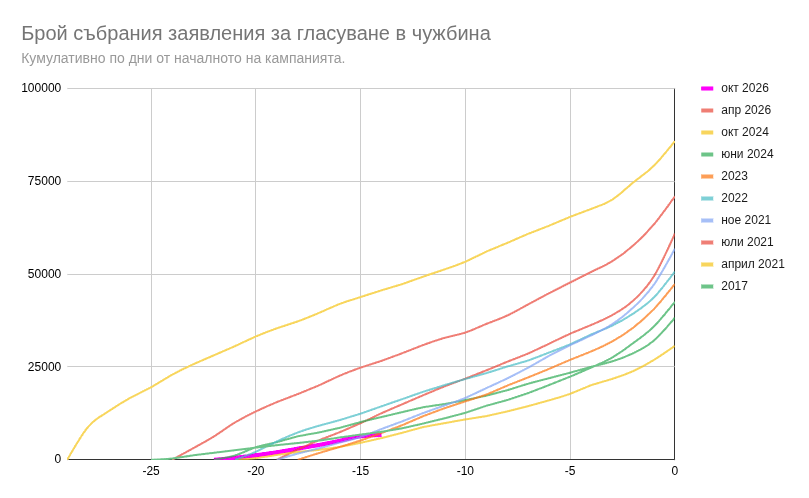
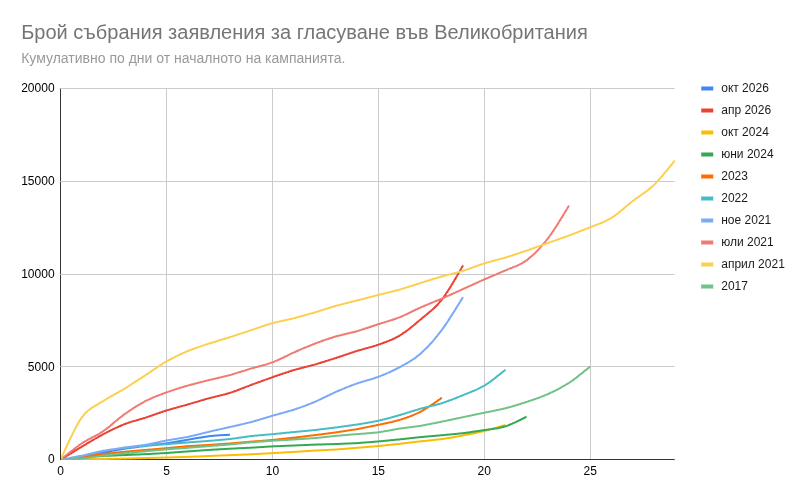
За този период са подадени почти 7000 заявления. Това са най-малко на този етап от кампанията за последните девет години. През 2017 г. имаше 5161 след седмица, а през октомври 2024 – 7284. Преди две годни обаче нямаше нужда от заявления, защото повечето секции зад граница се отваряха автоматично на база стара активност. Това беше силно ограничено преди парламентарния вот в началото на 2026 и все още не се случва за секции извън ЕС след последните промени.

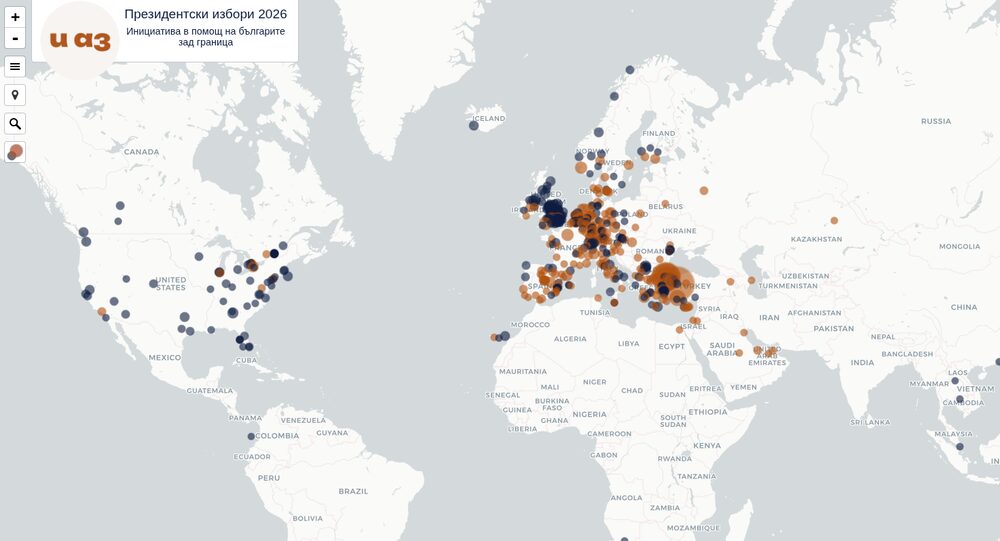
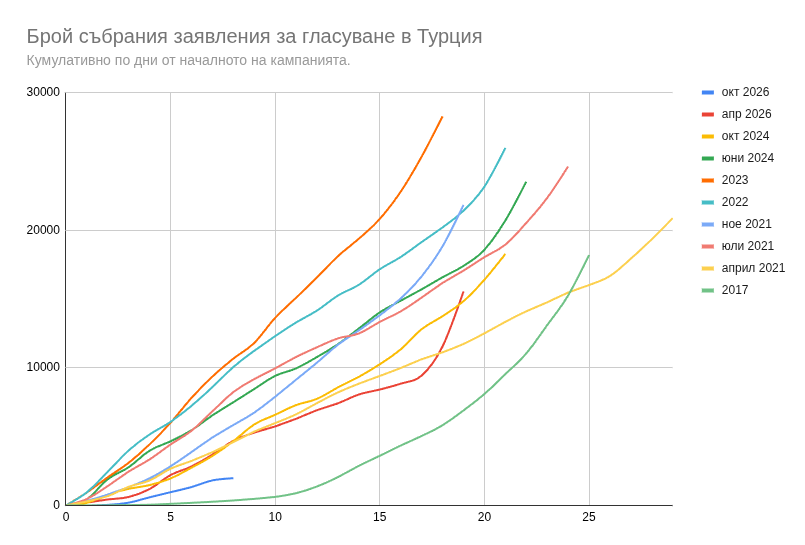
На Glasuvam.org ще намерите карта показваща в реално време къде са събрани колко заявления, както и подробна разбивка по места. На следващите две графики виждате сравнение в броя събрани заявления. Смятайки спрямо началото или края на кампанията пак виждаме, че е една от най-ниските активности в последните 10 вота.

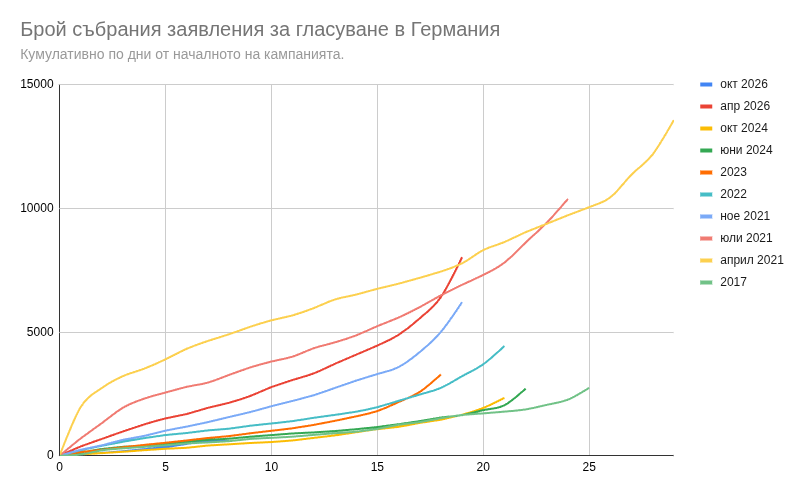
В Германия, където са одобрени доста секции автоматично, виждаме подобен спад в активността. Повече са от първата седмица при изборите през октомври 2024 и тези през 2017 г., но не с много. Пет пъти по-малко са събрани за седмица, отколкото през юли 2021 и 2.5 пъти по-малко от последния вот.

Във Великобритания положението е по-добре като единствено рекордните кампании от началото на 2026, април и юли 2021-ва са значително повече.

В Турция кампанията започва отчетливо различно от други години и се доближава до органичния растеж подобен на други държави по света като Германия и UK. Това е и причината броят заявления да е по-малък от всички вотове след 2017-та, когато почти нямаше заявления през първите 12 дни.

Остават две седмици до края на кампанията – 29-ти септември в полунощ българско време. Графиките горе показват, че в различни кампании е имало голямо увеличение на заявленията в последната седмица. На този етап обаче виждаме слаб интерес. Отчасти това може да се обясни с традиционно ниското внимание към президентските избори. Вярно е също, че липсва разбиране за промените на Избирателния кодекс, важността на подаването на заявления, както и отново всякаква информационна кампания от страна на ЦИК или МВнР за българите зад граница. Затова проекти като Glasuvam.org съществуват. Може да се регистрирате за бъдещи новини и събития.

Законите за дигитална България

Post Syndicated from Bozho original https://blog.bozho.net/blog/4630

Предлагаме 40 законопроекта за реална дигитализация. Дигиталната трансформация има за цел да осигури удобство за гражданите, оптимална работа на администрацията, прозрачност, ограничаване на корупционния риск и конкурентна среда за развитие на бизнеса.

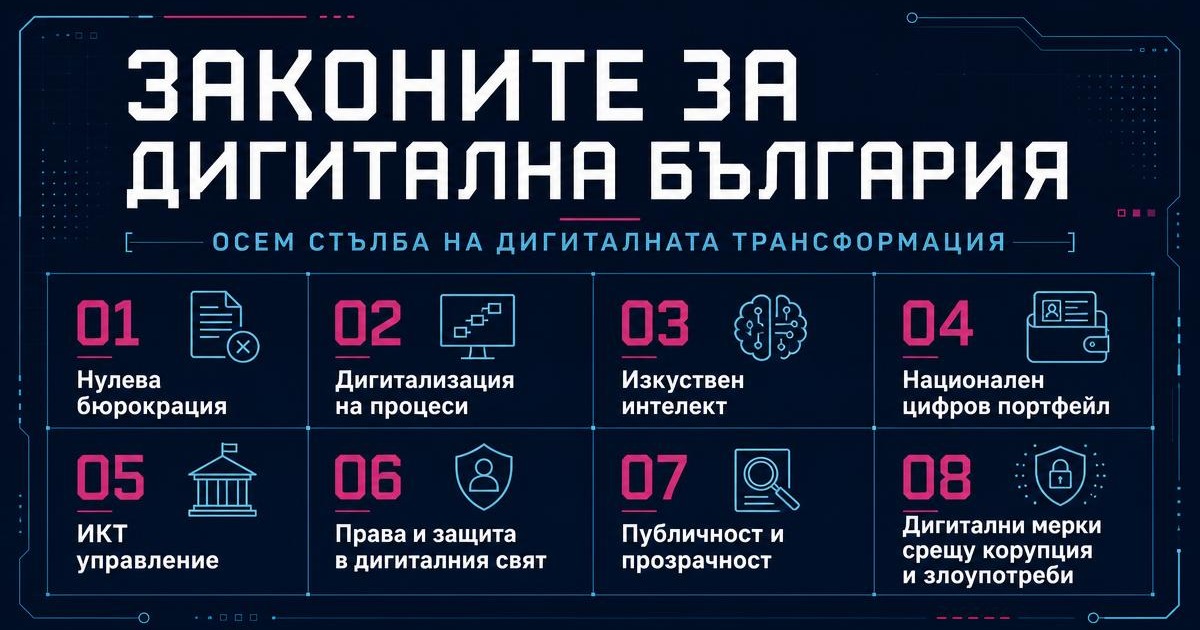
Затова предлагаме законодателна програма “Законите за дигитална България”, разделена на 8 групи, които можете да видите тук: digital.dabulgaria.bg. На същия адрес можете и да предлагате и нови инициативи, с които да допълним програмата. Ето накратко нашите предложения:

  1. Нулева бюрокрация – отпадане на излишни документи, хартийки, книжки, бележки, дневници и какво ли още не. В тази група има 9 законопроекта, за отпадане на здравноосигурителна книжка, отпадане на хартиения болничен лист, отпадане на удостоверенията за наследници и за липса на задължения, премахване на печата и изискването на печати, отпадане на стикери по автомобила, заявления за EORI номер, хартиени документи за таксиметрови превози, както и за дигитализиране на риболовния и ловния билет.
  2. Дигитализация на процеси – 10 законопроекта за преминаване от хартиени или полу-електронни процеси към изцяло електронни процеси – електронно досъдебно производство, електронен процес по инвестиционно проектиране и устройствено планиране, възможност за електронни нотариални производства, за електронна регистрация на автомобил, регистрация на фирма и производство за намена на чужденци. Въвеждане на електронни фактури и съхранение на електронни копия на хартиени фактури, пълна дигитализация на процесите по издаване на ТЕЛК, както и централизирано електронно проследяване на спазването на сроковете за произнасяне на всички администрации.
  3. Закона за използването и развитието на изкуствения интелект – цялостна уредба, свързана с прилагането на европейския регламент за искуствения интелект, както и използването на ИИ в публичния сектор, развитие на уменията на работниците и служителите за работа с ИИ, въвеждане на стимули за развитие на ИИ и ограничаване на рисковете.
  4. Национален цифров портфейл – въвеждане на единно приложение за достъп до електронни услуги, справки, кореспонденция с държавни органи, както и европейски портфейл за цифрова самоличност, вкл. възможност за представяне на личен документ през смартфон.
  5. Управление на ИКТ в обществения сектор – изцяло нов закон, който подробно да уреди как държавата и общините управляват информационните и комуникационните технологии – как ефективно да планират, възлагат и приемат резултати, така че използването на информационни технологии да не е тромаво, скъпо и безрезултатно усилие. Уреждане на ролята на системния интегратор и прозрачното възлагане.
  6. Права и защита в дигиталния свят – в процеса на дигитализация трябва да бъдат гарантирани основни права и защита на уязвими групи. По тази причина в тази група са включени законопроекти за защита на данните на шофьорите в тол-системата, защита на трафичните данни, криминализиране на шпионския софтуер, възможност за отказ от съхраняване на биометрични данни в МВР, възможност за лица с увреждания да ползват ефективно телефон 112, ограничаване на онлайн рекламата на хазарт, ограничаване на пристрастяващите елементи на социалните мрежи.
  7. Публичност и прозрачност – публикуването на колкото може повече данни за работата на държавата, особено когато става дума за разходване на публични средства, е изключително важна мярка – в тази група са включени законопроекти, с които администрацията се задължава да публикува данни за плащанията на НЗОК, плащанията на държавните дружества, земеделските субсидии, данните от системата за ветеринарен контрол (с цел ограничаване на фиктивните животни), отворени данни за ПТП, пътни нарушения и рецидивисти на пътя, както и увеличаване на данните в структуриран вид в Търговския регистър.
  8. Дигитални мерки срещу корупция и злоупотреби – дигитализацията сама по себе си е антикорупционна мярка, но в тази група са конкретни мерки, насочени срещу злоупотреби в различни сектори: дигитални мерки срещу корупцията в здравеопазването, мерки срещу имотните измами, ограничаване на фалшиви ТЕЛК-решения и измами с лични асистенти, както и ограничаване на злоупотребите със специални разузнавателни средства чрез дигитализация и повишаване на сигурността на процесите в органите, използващи СРС.

Част от законопроектите в тази законодателна програма вече са внесени. Други ще бъдат внесени след като бъдат обсъдени (системата, в която са качени, създадена с изкуствен интелект, позволява обществено обсъждане и призоваваме всеки да остави становище).

Тези 40 законопроекта са следваща стъпка, след десетките законопроекти и поправки, които бяха приети в последните няколко народни събрания по наше предложения (някои от тях: отпадане на трудова книжка, син талон, удостоверения и документ за платена такса с печат, въвеждане на единна входна точка за финансови отчети, пълна дигитализация на здравните данни, публичност на всички плащания на държавата, разширяване на публикуваните данни за обществени поръчки, изцяло електронно плащане на фишове, електронна връзка между НАП и КАТ, електронни документи в НЗОК, електронни ваучери за храна, служебно получаване на информация за местни данъци и такси от кадастъра и имотния регистър, отпадане на копието на електронни фактури, разширяване на електронните касови бележки и др.).

Не спираме с усилията за модернизация на страната, без значение дали сме управляващи или опозиция. Ако управляващите искат да правят правилните неща, няма да е достатъчно да напишат думата “дигитализация” няколко десетки пъти в програмата си – трябва ясен ангажимент, визия и приоритети.

Днес представяме такава визия, за която ще търсим подкрепа в парламента. Защото България има спешна нужда от модернизация и дигитална трансформация.

Материалът Законите за дигитална България е публикуван за пръв път на БЛОГодаря.

Последната предавка. Докъде ще стигне Никола Цолов?

Post Syndicated from original https://www.toest.bg/poslednata-predavka-dokude-shte-stigne-nikola-tsolov/

Последната предавка. Докъде ще стигне Никола Цолов?

На 27 август 2026 г. Никола Цолов стана първият българин, успял да седне зад волана на болид от Формула 1 в рамките на официални тестове. Той направи обиколки на легендарната писта „Енцо и Дино Ферари“ край Имола с автомобил на Racing Bulls – младшия тим в империята на Red Bull. След този исторически момент логичните очаквания са до края на 2026 г. да запише участие и в официална петъчна тренировка по време на състезателен уикенд от световния шампионат. Голямата цел обаче е през 2027-ма да го видим като редовен пилот на стартовата решетка – на самия връх в света на високите скорости.

За хората, които не следят отблизо моторните спортове, може би е трудно да разберат мащаба на това постижение.

България никога не е имала особени традиции в автомобилните пистови надпревари. Историческите изключения са по-скоро в сферата на ралитата – с пилоти от ранга на Илия Чубриков и Димитър Илиев – и много по-рядко в състезанията с болиди с открити колела (open-wheel).

В картинга през годините България е имала талантливи състезатели като Николай Върбицалиев (днес мениджър на Никола), а Пламен Кралев и Владимир Арабаджиев стигнаха до международни серии (съответно GP2 и Auto GP), но носеха по-скоро моментна тръпка на гордост за родните фенове, без реална възможност за пробив на най-високото стъпало. В мотоциклетизма нещата винаги са изглеждали малко по-обещаващо благодарение на успехите със супербайкове на Богдан Николов в миналото и на Мартин Чой днес. Обикновено обаче българските постижения са били в по-нишови дисциплини, като мотокрос, супермото и ендуро, където днес световния си пробив прави Теодор Кабакчиев.

Постиженията на всички тези спортисти заслужават огромно уважение, но значимостта на никое от тях не може да се сравнява с успеха на Цолов.

Никола е състезател в картинга още от дете и бързо става ясно, че границите на страната са тесни за таланта му. Когато започва да кара в Европейския шампионат по картинг, потенциалът му бързо привлича внимание. Двукратният световен шампион във Формула 1 Фернандо Алонсо го кани да карат заедно в маратонска надпревара за издръжливост, а впоследствие му подава ръка, осигурявайки му място в испанската Формула 4, в екипа на Адриан Кампос – мениджър с доказано око за бъдещи шампиони.

Никола доминира напълно в дебютния си сезон във Формула 4 и заслужено си печели сравнения с връстника си Андреа Кими Антонели, който по същото време изпреварва конкуренцията в италианския шампионат. Тук обаче пътищата им се разделят стратегически. Докато Антонели преминава през следващото стъпало – Формула Регионал (FRECA), Никола и мениджмънтът му вземат смелото решение да се хвърлят направо в дълбокото: преход директно към Формула 3 – една от сериите, която подгрява публиката в уикендите, когато има Формула 1.

За неопитния наблюдател този пропуск може да изглежда като бърз напредък, но разликата е драстична. Формула Регионал служи като мост, където пилотите свикват с по-тежки и по-мощни коли. Скачането от Формула 4 (където автомобилите са с около 160 к.с.) директно във Формула 3 (с 380 к.с. V6 двигател и масивна притискаща сила) е истински шок за тялото и предизвикателство за стила на шофиране.

Шампиони без броня. Нови примери за мъжественост от моторните спортове

Личи си, че Александър Драганов е запален почитател на моторните спортове. Но това не трябва да ни подвежда – статията му не е спортен коментар, а анализ на промените в представите за мъжественост в мотоциклетизма и Формула 1.

Първият сезон във Формула 3 е тежък за Цолов и за момент навява спомени за лимита, достигнат навремето от Кралев и Арабаджиев. Никола обаче навлиза в тази състезателна джунгла едва тийнейджър и с минимален опит с такъв тип машини. Първите му точки идват едва в края на неговата дебютна година. В следващия сезон обаче той печели съботния спринт в Княжество Монако – пистата, която се смята за най-големия тест за хладнокръвие и прецизност.

След Монако психологическата бариера пада. Редят се още победи, а за третата си година във F3 Цолов се премества в добре познатия си отбор на Campos Racing и – което е още по-важно – започва да кара с цветовете на академията на Red Bull. Това е същата структура, създала шампиони като Себастиан Фетел и Макс Верстапен.

2025 година се превръща в триумф за Никола Цолов. Той печели основното състезание в Монако със смазваща преднина и след серия от силни уикенди завършва като вицешампион във Формула 3. Първото място може би също щеше да е възможна цел, ако не беше дисквалификацията му в Австрия поради нарушение на строго техническо изискване за дебелината на пода на автомобила , под чийто удар през годините са попадали дори гиганти във Формула 1 като Mercedes, Ferrari и McLaren.

Въпреки изпуснатата титла постижението му осигурява заслужено място във Формула 2. А там Никола започва да плува в свои води от самото начало.

Цолов открива сезона през 2026 г. с победа в основното състезание на коварната писта „Албърт Парк“ в Мелбърн. Добавя към актива си спринта в Маями, отново превзема Монако (за трета поредна година!) и взема реванш на „Ред Бул Ринг“ в Австрия. Черешката на тортата са двете му победи на пистата „Силвърстоун“ във Великобритания. Начело на временното класиране, пред фаворити като Габриеле Мини и Рафаел Камара, Никола Цолов съвсем основателно кара феновете си да мечтаят той да стигне до Формула 1.

Мечта или реален шанс?

Дали обаче мястото на Цолов във Формула 1 е гарантирано? Или за пореден път падаме в познатия български капан да издигаме състезателите си в култ по време на младежките им години, за да ги сринем при първата грешка? Всички помним как Григор Димитров премина през целия спектър от народна любов до язвителни подигравки; как постоянството на Димитър Бербатов в „Манчестър Юнайтед“ беше подлагано на дисекция; или как волейболният ни национален отбор биваше обиждан в социалните мрежи след някой по-колеблив мач само година след като беше посрещнат на ръце след второто място на Световното във Филипините.

Това е горчива особеност на спортната ни култура (а и не само спортната, ако си помислим, примерно, за отношението към DARA, преди да спечели „Евровизия“ и след това) – да се обръщаме срещу своите при първата трудност и да ги хвалим само в дните на триумф. В професионалния спорт на подобно отношение се гледа с лошо око. Смисълът на подкрепата е да бъдеш зад спортиста, когато е трудно. Когато печели, е лесно за всеки.

Никола Цолов е изключителен талант, но дали ще стигне до самия връх не зависи единствено от темпото му на пистата.

Първата причина за високата ми оценка за него е финансовият контекст. Никола започна кариерата си при хронична липса на ресурси – за разлика от конкурентите си. Доколкото мога да преценя от публично достъпна информация, семейството му не е бедно спрямо българските стандарти, но повечето му съперници идват от мултимилионерски фамилии с огромно влияние. Бащата на Кими Антонели е бивш GT състезател с контакти в тази сфера, а синът му беше финансиран от Mercedes още от детска възраст. Ландо Норис и Оскар Пиастри са подкрепяни от изключително заможни семейства, а Йос Верстапен даде на сина си Макс безпрецедентна методическа и материална подготовка. Никола притежаваше неоспорим потенциал от малък, но без намесата на Фернандо Алонсо кариерата му можеше да приключи преждевременно. Алонсо обаче е прагматик – той не влага името и парите си в пилоти без перспектива. Същото важи с още по-голяма сила за д-р Хелмут Марко. Човекът, който ръководи младежката програма на Red Bull, е известен с безпощадния си подход – той без колебание освобождава пилоти и задържа само онези, които вижда като бъдещи световни шампиони.

Втората причина са самите резултати. Доминацията във Формула 4, серията от победи в Монако и фактът, че още в дебютния си сезон във Формула 2 Никола се бори за титлата, го поставят в категорията на феномени като Шарл Льоклер и Джордж Ръсел. Това вече не е просто български пилот, подкрепян от сънародниците си по патриотични подбуди, а един от най-търсените млади състезатели на планетата.

Третата причина е начинът, по който той печели. Макар все още да изпитва леки колебания в чистата скорост за една обиколка по време на квалификация, Никола разви едно от най-ценните умения в съвременния автомобилизъм – той е т.нар. tire whisperer („властелин на гумите“). Никола успява да съхрани структурата и температурата на гумите до съвършенство, запазвайки ресурс за атака в последните обиколки, когато съперниците му вече „се пързалят“. Към това трябва да добавим и изключително агресивния му стил в директните единоборства. Понякога тази агресия прекрачва границата, водейки до контакти и съответно до наказания (често при спорни ситуации), но именно непримиримият характер на Никола го прави опасен за конкурентите му на пистата.

В същото време стартовете в Унгария и Мадрид показаха, че тази непримиримост може да бъде и слабост – нежеланието да се приберат сигурните точки и рискованите маневри за позиции, които не са жизненонеобходими, вероятно направиха интригата за титлата във Формула 2 по-голяма, отколкото можеше да бъде. Това е нормално, когато говорим за млади пилоти под напрежение, но и слабост, която за в бъдеще ще трябва да бъде отстранена, без обаче да се загуби естественият за всеки състезател хъс за печелене на позиции.

Кадровият пъзел във Формула 1

Какво обаче е бъдещето? На всички ни се иска Никола да достигне до Формула 1. Талантът обаче, макар и необходим, сам по себе си не е достатъчен.

Пример за това е Алекс Палоу – пилот с феноменално умение да пази гумите, подобно на Никола. Палоу стана петкратен шампион в американските серии IndyCar, но така и не получи реален шанс за титулярно място във Формула 1 просто защото не попадна в правилната програма в правилния момент.

Най-логичният път за Никола минава през Racing Bulls. За да се освободи място там обаче, Red Bull трябва да пренаредят пилотите си. Дебютантът Арвид Линдблад се представя силно и зад него стои влиятелната британска лобистика в моторспорта. В същото време Лиъм Лоусън прави много силен сезон и уволнението му изглежда слабо вероятно. Някой от тях да бъде повишен с изпращане в основния отбор на Red Bull Racing също е трудна задача, тъй като Макс Верстапен е сърцето на цялата империя, а Исак Хаджар се утвърждава като идеалния втори пилот.

Шампиони по свой начин – да бъдеш себе си на подиума

Как един политолог анализира спортни състезания? С присъщата си самоирония Александър Драганов се чуди защо два пъти е излязъл прав, че има промяна в представите за мъжественост в моторните спортове. Но и спрелият часовник е верен два пъти в денонощието, нали?

Вариантът Никола да бъде отдаден под наем на друг отбор във Формула 1 е сложен. Red Bull е технически обвързан с Ford за новите си задвижващи системи от 2026 г., докато останалите отбори са свързани с конкуриращи се гиганти като Mercedes, Ferrari, Audi, Honda или General Motors (с марката Cadillac).

Ако Никола спечели титлата във Формула 2, правилата на FIA му забраняват да остане в тази категория. Тогава пред него се разкриват няколко пътя:

  1. Резервен пилот във Формула 1: Работа в симулатора на Red Bull, присъствие във всеки бокс и участия в петъчните тренировки. Това го позиционира идеално за неочаквана рокада, но за феновете (а и за самия него) това ще бъде година на пасивно и тягостно очакване.
  2. Преминаване в друг елитен шампионат: Временна крачка встрани, която обаче държи състезателния рефлекс буден. Вариантите тук са японската Super Formula (където колите по скорост са най-близо до F1), класът Hypercar в Световния шампионат за издръжливост (WEC) и навлизащата в изцяло нова, по-мощна ера Формула Е.

Преминаване в американския IndyCar изглежда по-малко вероятно – макар шампионатът да е изключително атрактивен, опитът с Палоу показва, че презокеанският преход прави завръщането към Европа и Формула 1 почти невъзможно.

Най-елегантният вариант остава раздвижване на пазара: Лиъм Лоусън да премине в друг отбор от решетката (тъй като шансовете му за завръщане в основния тим на Red Bull са ограничени заради недобрите му резултати през 2025 г.), което отваря свободно място в Racing Bulls. Това е най-реалистичният сценарий Цолов да влезе във Формула 1 още следващия сезон.

Наследството на един специален талант

Каквото и да се случи оттук нататък в тази шахматна партия, направеното от Никола Цолов вече е безпрецедентно за българския спорт. Феновете му дължат подкрепа не само в дните на триумф, но и тогава, когато резултатите не са такива, каквито им се иска.

Преди много години легендарният рали пилот Илия Чубриков издаде мемоарната си книга „От Бичкинята до Монте Карло“, описвайки пътя от родния си край до най-престижното рали в света. Никола Цолов кара на писта, но с трите си победи по улиците на Монако, когато над „Ла Кондамин“ звучеше българският химн, той символично довърши пътя, започнат от бай Илия.

Никола изкачи българския автомобилен спорт на върхове, за които допреди броени години българските почитатели на моторните спортове не са смеели и да мечтаят. И го стори, разчитайки предимно на собствения си талант и характер – което прави цялата история още по-красива. А най-хубавото е, че най-вълнуващите глави от нея може би тепърва предстои да бъдат написани.

GNU Core Utilities 9.12 released

Post Syndicated from jzb original https://lwn.net/Articles/1094312/

Pádraig Brady has announced
GNU Core Utilities (coreutils) version 9.12. “There have been 288 commits by
16 people in the 21 weeks since 9.11
“. New features include an -A
option for uname
which labels all output, as well as adding awareness of the failfs and nullfs filesystem types to stat
and tail.

There are many bug fixes in this release as well, including one for a bug “present
in ‘the beginning’
” that caused some utilities to fail when traversing
hierarchies if files are being removed in parallel.

Upcoming Speaking Engagements

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/upcoming-speaking-engagements-60.html

This is a current list of where and when I am scheduled to speak:

Note: the Elevate Festival talk listed in last month’s newsletter is canceled.

The list is maintained on this page.

AWS Security Reference Architecture: A deep dive into PCI DSS compliance

Post Syndicated from Avik Mukherjee original https://aws.amazon.com/blogs/security/aws-security-reference-architecture-a-deep-dive-into-pci-dss-compliance/

Amazon Web Services (AWS) is excited to announce the publication of the AWS Security Reference Architecture (AWS SRA) Payment Card Industry (PCI) Data Security Standard (DSS) Deep Dive. This new guide extends the core AWS SRA to provide prescriptive, architecture-level guidance for organizations that store, process, or transmit cardholder data on AWS.

Organizations subject to PCI DSS have long asked for a comprehensive reference that bridges the gap between general AWS security best practices and the specific technical and organizational controls required to achieve and maintain PCI DSS compliance. This guide answers that need by showing how AWS SRA patterns address PCI DSS intent from account scoping and network segmentation to encryption, logging, and access control.

What is the AWS SRA PCI DSS Deep Dive?

The AWS SRA is a holistic, prescriptive security architecture guide that describes how AWS security services fit together across a multi-account AWS environment. It’s built around a modular, three-tier web architecture and is intentionally designed to be adapted as needed. Not every workload needs every service, but the AWS SRA provides the full range of options and their architectural relationships.

This PCI DSS deep dive doesn’t replace the AWS SRA, it extends it:

  • Mapping AWS SRA account types to PCI DSS scoping boundaries showing which accounts are in scope, connected-to or security-impacting, or out-of-scope in a typical payment architecture.
  • Layering PCI-specific controls onto existing AWS SRA service configurations. For example, additional logging granularity, encryption requirements, or network restrictions that go beyond the AWS SRA baseline.

The architectural patterns and controls described in this guide apply equally to merchants and service providers.

Who should use the guide

The guide is intended for:

  • Security architects designing or extending an AWS multi-account landing zone for workloads under PCI DSS scope.
  • Compliance engineers mapping AWS controls to PCI DSS requirements during assessment.
  • Cloud platform teams building shared security services that must accommodate a cardholder data environment (CDE).
  • Qualified Security Assessors (QSAs) and Internal Security Assessors (ISAs) who want to understand how AWS SRA patterns address PCI DSS intent.

Key AWS SRA design principles for PCI DSS

The guide applies six foundational AWS SRA design principles that are particularly relevant to PCI DSS compliance:

  • Implement a strong identity foundation: Enforce least privilege, separation of duties, and centralized identity management. Eliminate reliance on long-term static credentials.
  • Enable traceability: Monitor, alert, and audit actions in real time. Integrate log and metric collection with automated investigation and response systems.
  • Apply security at all layers: Defense-in-depth with preventive and detective controls at edge, virtual private cloud (VPC), load balancing, compute, OS, application, and code layers.
  • Protect data in transit and at rest: Classify data by sensitivity and apply encryption, tokenization, and access control mechanisms.
  • Keep people away from data: Reduce or eliminate direct access to cardholder data through automation and tooling.
  • Prepare for security events: Establish incident management processes, run simulations, and implement automated detection and recovery.

How to use the guide

The AWS SRA PCI DSS deep dive can be consumed in two ways:

  • As a narrative: Read the guide from beginning to end, starting with the PCI DSS primer, through the architecture and account scoping model, to the detailed requirement mappings. This approach gives you a complete understanding of how AWS SRA and PCI DSS intersect.
  • As a reference: Navigate directly to specific PCI DSS requirements or AWS SRA account types relevant to your current project. The guide includes architecture diagrams, requirement mapping tables, and service-specific configurations that you can use independently.

The guide includes downloadable architecture diagrams and detailed control mapping tables that complement the narrative content, making it straightforward to reference during security reviews and PCI DSS assessments.

Next steps

Security is a journey, not a destination. Review the AWS SRA PCI DSS Deep Dive guide and begin mapping its patterns to your own cardholder data environment and then validate existing environments against SRA best practices using SRA verify.

If you need assistance, contact AWS Professional Services, your AWS account team, or the AWS Partner Network, who can work with you to translate the reference architecture into a customized AWS environment that you can then operate.

If you have feedback about this post, submit comments in the Comments section below. If you need assistance architecting or implementing a PCI DSS-compliant AWS environment, contact the AWS Security Assurance Services team.


Author

Avik Mukherjee

Avik is a Senior Security Solutions Architect with more than a decade of experience in IT governance, security, risk, and compliance across retail, financial, and technology industries. He’s one of the original authors of the AWS Security Reference Architecture and leads the effort to extend the AWS SRA to compliance frameworks.

Akanksha Chaturvedi

Akanksha is a Senior Security Assurance Consultant with over 10 years of specialized experience in risk-based security assessments and regulatory compliance across highly regulated industries. She is an expert practitioner in HIPAA, PCI-DSS, GDPR, FedRAMP, and IRAP frameworks, with demonstrated success in architecting and deploying enterprise security programs from conception through full implementation.

Nimesh Ravas

Nimesh Ravasa

Nimesh is a Senior Assurance Consultant at AWS who focuses on security assurance and compliance for cloud-centered architectures. He brings extensive experience in PCI DSS assessments and security architecture reviews, helping organizations build and maintain compliant environments on AWS. He is passionate about translating complex compliance requirements into actionable technical guidance.

Omner Barajas

Omner Barajas

Omner is a Senior Security Solutions Architect at AWS with deep expertise in designing secure, scalable architectures for regulated industries. He specializes in network security, identity management, and security automation, and works with customers across financial services and payments to implement defense-in-depth strategies aligned with industry standards.

Viktor Mu

Viktor Mu

Viktor is a Senior Assurance Consultant at AWS with a strong background in information security governance, risk, and compliance. He specializes in helping organizations achieve and maintain PCI DSS compliance in complex cloud environments, with particular expertise in scoping, segmentation, and continuous compliance monitoring.

Validating multi-agent decisions with Step Functions and Bedrock AgentCore

Post Syndicated from Ben Freiberg original https://aws.amazon.com/blogs/compute/validating-multi-agent-decisions-with-step-functions-and-bedrock-agentcore/

For an airline operations team, a single flight cancellation sets off a chain reaction. Hundreds of passengers need new itineraries within minutes, and no two cases are alike. They have different loyalty tiers, sit on different fare rules, and have downstream connections that may not wait. Passengers have varying cabin and seat preferences and might fall under different regulatory entitlements depending on where they booked and where they are flying.

Most airlines handle this with a layered system: rule-based automation covers the simple, one-hop rebooks, and everything else flows to a manual queue staffed by service agents. That works when disruptions are isolated. When they are not, the queue overwhelms, waiting times spike, and passengers booked alternatives themselves that create downstream knock-on disruptions.

This is exactly where AI agents become compelling. An agent can reason across seat availability, fare rules, loyalty entitlements, and connection timing the way an experienced desk agent would, but at machine speed and across hundreds of cases in parallel. Multi-agent collaboration typically lets a supervisor agent route work to collaborator sub-agents, with the model itself deciding which sub-agent runs and in what order. But an unconstrained agent might optimize for the passenger’s preference while ignoring a codeshare restriction, rebook onto a flight that meets minimum connection time on paper but not at that specific airport, or calculate compensation under the wrong regulatory regime because it misread the ticket’s point of sale.

Orchestrating specialized Amazon Bedrock AgentCore agents with AWS Step Functions gives you the reasoning power of generative AI with the guardrails of deterministic validation. Step Functions adds native fan-out across thousands of passengers, a callback pattern that pauses a case for human review at zero compute cost, and a durable execution history that serves as your audit trail. The principle is that agents propose, and deterministic code validates. The pattern is demonstrated here for airline rebooking, but it applies anywhere automated decisions can have real financial or regulatory consequences.

Solution overview

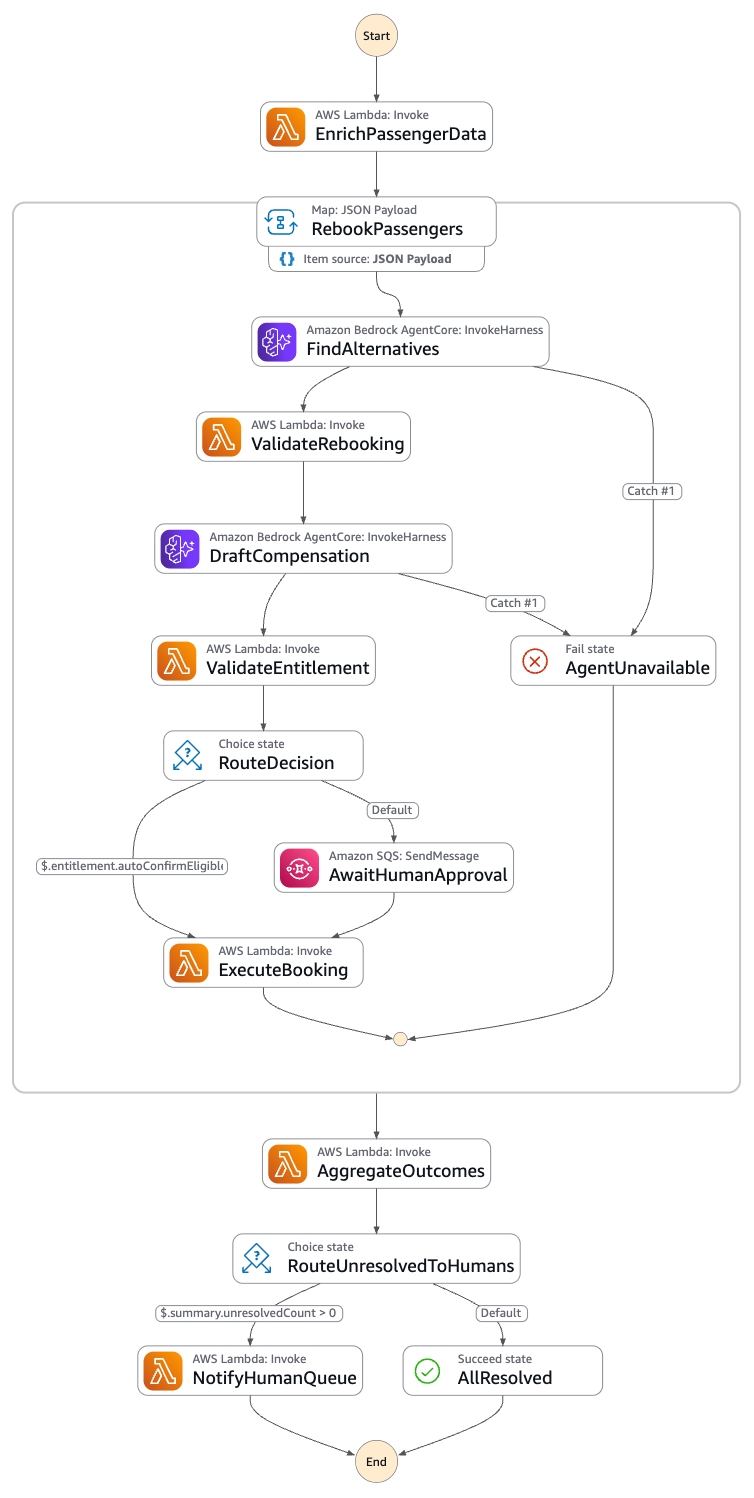
The design is a Step Functions state machine where deterministic steps that map to the business processes wrap each agent’s non-deterministic behavior. The following diagram shows the end-to-end flow. At a high level, the workflow proceeds through these stages:

  1. The workflow starts when a flight-cancellation event arrives, for example through an Amazon EventBridge integration.
  2. An enrichment step pulls additional data such as the passenger manifest, current bookings, loyalty status, and stored preferences.
  3. The workflow fans out to run agents in parallel for each affected passenger.
  4. Two agents then run for each passenger: a find-alternatives agent proposes the top three rebooking options, and a compensation agent determines entitlement based on route, delay duration, and cause.
  5. A deterministic validation step runs after each agent, confirming flights are actually bookable and entitlement rules are followed before either result is used.
  6. The workflow checks whether the case can be auto-confirmed, or needs human review.
  7. Bookings are confirmed, compensation issues, and confirmations are sent. Unresolved cases go to human agents.

The key principle: no agent Task state writes to the reservation system or issues a payment. Only deterministic Task states do that, and only after a deterministic validation step has passed.

Integrating AgentCore harness with Step Functions

AgentCore harness is a managed agent loop. You specify a model, system prompt, and tools, and the harness runs the reasoning cycle (model calls, tool execution, memory management, and response generation) end-to-end in a single API call. It handles the intra-agent orchestration so that Step Functions can focus on inter-agent orchestration: fan-out, sequencing, validation gates, and exception routing. Step Functions provides a native optimized integration for AgentCore harness, which calls InvokeHarness against a target HarnessArn. The optimized integration gives you an extended per-Task timeout of 15 minutes (900 seconds), so agents have enough time to reason through complex proposals. The trade-off is that the agent call is request-response only. There is no .sync and no .waitForTaskToken on the agent step, and only the final assistant message is returned to the state machine.

The following Amazon States Language snippet shows the optimized harness invocation inside a Distributed Map. For the full definition, see the sample on Serverless Land.

{
  "Comment": "Illustrative - per-passenger rebooking fan-out",
  "StartAt": "RebookPassengers",
  "States": {
    "RebookPassengers": {
      "Type": "Map",
      "ItemProcessor": {
        "ProcessorConfig": { "Mode": "DISTRIBUTED", "ExecutionType": "STANDARD" },
        "StartAt": "FindAlternatives",
        "States": {
          "FindAlternatives": {
            "Type": "Task",
            "Resource": "arn:aws:states:::bedrockagentcore:invokeHarness",
            "Parameters": {
              "HarnessArn": "<HARNESS_ARN>",
              "RuntimeSessionId.$": "$.passenger.sessionId",
              "Messages": [{ "Role": "user", "Content": [{ "Text.$": "States.JsonToString($.passenger)" }] }]
            },
            "TimeoutSeconds": 900,
            "ResultPath": "$.proposal",
            "Next": "ValidateRebooking"
          },
          "ValidateRebooking": { "Type": "Task", "Resource": "arn:aws:states:::lambda:invoke", "End": true }
        }
      },
      "MaxConcurrency": 1000,
      "End": true
    }
  }
}

Note: the service name is spelled bedrockagentcore (no hyphen) in the Step Functions resource string, but bedrock-agentcore (with a hyphen) in the AgentCore ARN.

MaxConcurrency is set to 1000 to bound fan-out and protect downstream booking and inventory systems. If you omit it or set it to 0, you get the default behavior, which runs up to 10,000 parallel child executions. The agent Task flows directly into a deterministic validation Task.

How it differs from managed multi-agent collaboration

Multi-agent collaboration typically means that a supervisor agent decides which sub-agent runs and which tools it calls. Step Functions moves those decisions out of the agent layer entirely.

This design puts orchestration, fan-out, validation, routing, retries, and the audit trail into Step Functions instead. Routing is a deterministic state you define and can test in isolation, not a model classification you hope will be consistent. You get a per-state execution history (every transition recorded with input and output), whereas agent-layer traces require opt-in and provide reasoning rationale rather than a durable, always-on event log.

Design walkthrough of the reference app

The following image shows the Step Functions state machine implemented by the sample application.

Step Functions state machine showing the rebooking workflow: trigger, enrich, a Distributed Map fan-out with agent and deterministic validation stages, choice routing to human review, and execute stages

Figure 1: The Step Functions state machine for the airline rebooking workflow

Stage 1, Trigger. An Amazon EventBridge rule starts the workflow on a flight-cancellation event.

Stage 2, Enrich. A deterministic Task pulls the passenger manifest, bookings, loyalty status, and preferences into the execution state.

Stage 3, Map fan-out. A Distributed Map iterates affected passengers in parallel. The choice of Map type matters at scale. An inline Map runs up to 40 concurrent iterations, which is the documented threshold for choosing Distributed mode. A Distributed Map runs up to 10,000 parallel child executions by default, the right tool when a hub event affects thousands of passengers.

Stage 4, Agent 1 find alternatives. An AgentCore Task proposes the top three options, reasoning over the passenger’s preferences and constraints.

Stage 5, Deterministic validation of the rebooking proposal. An AWS Lambda Task confirms each proposed flight is bookable by checking live availability, fare rules, and route validity, and it rejects hallucinated options. An agent might confidently propose a flight that does not exist. This stage is where that proposal is caught before it can become a ticket.

Stage 6a, Agent 2 draft compensation. A second AgentCore Task drafts personalized, customer-facing notification text only. It does not compute entitlement and it does not move money.

Stage 6b, Deterministic entitlement check. A Lambda Task computes and validates the entitlement against rule tables before any compensation issues. Consumer-protection frameworks such as EU Regulation 261/2004 (EU261) and US Department of Transportation refund rules are referenced here illustratively, to show why deterministic, auditable computation matters. The specific bands, triggers, and amounts are configuration you own and validate against current legal guidance, not something an agent should infer.

Stage 7, Choice routing and human-in-the-loop. A Choice state auto-confirms rebookings for some passengers and routes the rest to a human. For the cases that need review, the workflow waits on a separate .waitForTaskToken Task, backed by Lambda, Amazon Simple Notification Service (Amazon SNS), or Amazon Simple Queue Service (Amazon SQS), with a 4-hour timeout. The wait happens on this separate callback Task, never on the agent step.

{
  "Comment": "Illustrative - route and wait on a human, not on the agent",
  "RouteDecision": {
    "Type": "Choice",
    "Choices": [
      {
        "Variable": "$.passenger.autoConfirmEligible",
        "BooleanEquals": true,
        "Next": "ExecuteBooking"
      }
    ],
    "Default": "AwaitHumanApproval"
  },
  "AwaitHumanApproval": {
    "Type": "Task",
    "Resource": "arn:aws:states:::sqs:sendMessage.waitForTaskToken",
    "Parameters": {
      "QueueUrl": "https://sqs.us-east-1.amazonaws.com/123456789012/approvals",
      "MessageBody": {
        "taskToken.$": "$$.Task.Token",
        "passengerId.$": "$.passenger.id",
        "options.$": "$.proposal.validatedOptions"
      }
    },
    "TimeoutSeconds": 14400,
    "Next": "ExecuteBooking"
  }
}

Stage 8, Execute. Deterministic Task states confirm the booking, issue compensation, and send confirmation. Each execution Task derives an idempotency token from the passenger ID combined with the decision ID (the child execution name, or a hash of the validated option set) and passes it to the booking and payment APIs, so a retry or redrive is a no-op instead of a duplicate booking or a second payment.

Stage 9, Aggregate and exception routing. The workflow summarizes outcomes and routes any unresolved cases to human agents.

The validation step itself is ordinary deterministic code. A simplified rebooking validator in Python looks like the following.

# Illustrative - reject any option the agent proposed that is not bookable
def handler(event, context):
    passenger = event["passenger"]
    proposed = event["proposal"]["options"]

    validated = []
    for option in proposed:
        flight = lookup_flight(option["flightId"])
        if flight is None:
            continue  # hallucinated or stale flight, reject
        if flight["seatsAvailable"] < 1:
            continue  # no inventory, reject
        if not fare_rules_allow(passenger["fareClass"], flight):
            continue  # fare rule violation, reject
        if not route_is_valid(passenger["origin"], passenger["destination"], flight):
            continue  # invalid route, reject
        validated.append(option)

    return {
        "passengerId": passenger["id"],
        "validatedOptions": validated,
        "autoConfirmEligible": passenger["loyaltyTier"] == "top" and len(validated) > 0,
    }

Best practices and guardrails

Reject hallucinations through validations. No agent proposal is applied without a deterministic validation step passing first. This minimizes the impact of hallucinations, prompt injections, or bugs on your workflow.

Keep a complete audit trail. Step Functions execution history records every state transition, input, and output, and pairing that with durable persistence gives you a per-decision record. You can show exactly which proposal was made, which validation passed or failed, and who approved the exception.

Surface only true exceptions to humans. Humans handle only what validation or the agent cannot resolve. Auto-confirmation handles the clear cases, and people spend their attention on the genuinely ambiguous ones.

Hold executions open cheaply. The .waitForTaskToken callback holds the execution open with no compute charges while the execution is paused. For example, you can cost-efficiently park thousands of pending approvals overnight. Refer to the AWS Step Functions pricing page for current details.

Make execution idempotent. Guard reservation execution and compensation issuance against retries and double-sends, as shown in Stage 8. Derive the idempotency token from the passenger ID and decision ID, and pass it to your booking and payment APIs so that a replay is a no-op.

Respect cost and timeouts. Keep each per-agent Task timeout within the 15-minute quota, bound your Map concurrency to protect downstream systems, and track the token usage returned in the agent response so you can attribute and forecast cost.

Handle errors deliberately. Apply Retry and Catch on the agent Tasks for conditions such as BedrockAgentCore.ThrottlingException and BedrockAgentCore.ResourceNotFoundException, and on the Lambda validation Tasks for their own failure modes. A Catch on an agent Task can route a stuck passenger straight to the human queue rather than failing the whole child execution.

Confirm availability and Region support. Check the current availability status and supported AWS Regions for AgentCore and the Step Functions integration at the AWS Capabilities by Region on Builder Center.

Conclusion

A flight-cancellation event is a challenging test of automated decision-making, because the output can have immediate financial impact. The way to use AI agents safely in that setting is to let them do what they are good at, proposing options and drafting language, while never letting a proposal become an action until deterministic code has approved it. In this design, orchestration, fan-out, validation, routing, and retries are implemented in Step Functions rather than inside an agent’s reasoning. Agents do not make changes directly, and their output is only applied after deterministic validation. You get a per-decision record for review, and you hold exceptions open on a callback that adds no compute or storage cost while it waits.

To get started, deploy the reference pattern from Serverless Land and adapt the validation layer to your own workflow.

Dell Pro 5 16 (AMD) Laptop Review

Post Syndicated from Ryan Smith original https://www.servethehome.com/dell-pro-5-16-amd-laptop-review/

Today we are taking a look at Dell’s 16-inch laptop for mainstream business segment, the AMD-based Dell Pro 5 16. The pro laptop hits all the high notes, pairing an AMD Ryzen AI 9 HX PRO 470 processor with great modularity and a good balance between size, weight, and performance

The post Dell Pro 5 16 (AMD) Laptop Review appeared first on ServeTheHome.

Using AI for Weapons Development

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/using-ai-for-weapons-development.html

Last week, Anthropic released a long and detailed document describing current misuses of their Claude models. I’m still reading it, but I wanted to flag this:

We identified a cell of threat actors based in northern Yemen running three weapons development programs: a guided rocket that used a commodity phone-class flight computer with final-phase homing guidance; a multi-stage ballistic missile with a stated range goal above 2,000 km; and a multi-variant missile (referred to as the “R2000” set) that included a hypersonic glide vehicle variant.

The actors used Claude Code in place of human software engineers to develop the guidance, navigation, and control (GNC) software that steers and stabilizes a flying vehicle. For example, they used Claude to integrate an open-source autopilot onto a phone-class flight computer, writing the control and position estimation software, tuning the control settings, running a firmware build pipeline, and performing a flight simulation. The actors managed several Claude instances at once, assigning each one a role, much as a lead would delegate work on a small engineering team: the actors tasked one instance with writing the code, another with research, and a third with reviewing the code the first instance produced.

Our safeguards blocked many of their requests, but not all of them. The actors used a variety of tactics to evade our safeguards, including hiding their goals and the products the software was meant for, and they split their work across multiple sessions so no single session revealed their full intent.

These actors carried out a sustained effort to develop guided weapons, including using Claude to design guidance software. We do not have evidence the actors succeeded in fielding an operational device; but they did test-fire a guided rocket. This field test appears to have failed: within hours, the actors returned to Claude to work out why it failed.

Expect more of this. AI systems democratize expertise and capability. Most of the time that’s a good thing, but sometimes it’s not.

AWS Weekly Roundup: OpenAI GPT-6 Astra on Amazon Bedrock, Amazon Quick desktop GA, Kiro for students, and more (September 14, 2026)

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-openai-gpt-6-astra-on-amazon-bedrock-amazon-quick-desktop-ga-kiro-for-students-and-more-september-14-2026/

There’s a particular energy to mid-September in New York. Pumpkin spice lattes are flowing, temperatures are dropping, and it’s nearly sweater weather. The city is back at full speed, and so is the AWS launch calendar. This week that energy showed up in a new frontier model on Amazon Bedrock, a desktop app for Amazon Quick, and a reminder that the developers seeing the biggest gains from AI agents aren’t just using better tools — they’re working differently.

Let’s dive in.

Headlines
OpenAI GPT-6 Astra is now generally available on Amazon Bedrock – GPT-6 Astra is OpenAI’s latest and most capable model to date, and you can now run it on Amazon Bedrock. It brings deeper reasoning and judgment, professional-quality writing and design, and advanced computer and browser use to demanding business workflows. The model supports a context window of up to 1 million input tokens, so you can send it large codebases, long contracts, or extensive document collections and ask it to reconcile competing inputs.

You can call GPT-6 Astra through supported Amazon Bedrock APIs, or configure ChatGPT Work and Codex to use the model on Amazon Bedrock. Alongside the launch, OpenAI is introducing new enterprise plugins for ChatGPT Work that extend Astra’s browser-use capabilities across common business applications. Established AWS controls help you secure workloads, govern access, and audit model invocation activity, and your inference data isn’t used for model training. Read more

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

  • Amazon Quick desktop app is now generally available on macOS and Windows – The Amazon Quick desktop app brings Amazon Quick to your computer, where it can work with local files and stay connected to your calendar, email, and business apps in the background. Conversations, context, and agents stay synchronized across desktop and mobile, so work you start on one surface carries over to the other. With this release, Quick agents also keep running after you close your computer, which means you can start a long-running task before you leave the office, add input from the mobile app on the way home, and review the result when you get there. Existing Quick users can download the desktop app, and the mobile app is available from the Apple App Store and Google Play. Read more
  • AWS Lambda now supports a 90-minute function timeout on Lambda Managed Instances – You can now configure a function timeout of up to 90 minutes for asynchronous and event source mapping (ESM) invocations on Lambda Managed Instances, a 6x increase from the previous 15-minute limit. That opens the door to data processing, media transcoding, financial calculations, AI inference, and batch jobs that need longer continuous execution, without splitting the work across multiple functions. Synchronous invocations keep the existing 15-minute maximum. The longer timeout also applies to steps inside Lambda durable functions, which can still run for up to a year when invoked asynchronously. Read more
  • Amazon EBS Volume Clones now copies volumes across accounts – Amazon Elastic Block Store (Amazon EBS) Volume Clones can now copy a volume into another AWS account and re-encrypt it with an AWS Key Management Service (AWS KMS) key in the target account. If you keep production and development in separate accounts, you can share a volume with AWS Resource Access Manager (AWS RAM) and let the target account create a fresh copy in the same Availability Zone, for example, cloning a production database volume into an isolated development account. Cross-account copy works for all volume types, including unencrypted volumes and volumes encrypted with customer managed keys. Read more
  • Second-generation single-rack AWS Outposts is now generally available – The new single-rack AWS Outposts is a self-contained 42U rack that puts compute, storage, and networking into one compact unit for locations that need low latency, local data processing, or data residency, and don’t have room for a larger footprint. A single rack delivers up to 2,688 vCPU and 100 TB of Amazon EBS storage, and supports the latest x86-powered Amazon EC2 instances, including general purpose (M7i, M8i), compute-optimized (C7i, C8i), memory-optimized (R7i, R8i), and Outposts accelerated networking instances. You get the same APIs, console, automation, governance, and security controls as multi-rack Outposts and AWS Regions. Read more
  • Amazon OpenSearch Serverless is now available on v0 by Vercel – You can now describe a search or AI application in natural language inside v0 by Vercel and get a full-stack app backed by Amazon OpenSearch Serverless. v0 provisions a collection, indexes your data, and uses the OpenSearch Serverless endpoint for full-text search and vector search for retrieval-augmented generation (RAG) workloads, without leaving the v0 interface. OpenSearch Serverless scales capacity up and down for you, so you can focus on the application instead of cluster management. You can provision under a new AWS account or link an existing one. Read more
  • AWS Transform for .NET modernization is now generally available via CLI – You can trigger an AWS-managed .NET modernization in AWS Transform custom with a single CLI command, then run it interactively or script it into an existing pipeline. The CLI sits alongside the existing AWS Transform for .NET experiences in the web application, Visual Studio IDE, Kiro Power, and MCP agents. Use it to upgrade language versions, migrate frameworks, optimize performance, and analyze codebases with transformations you can run as-is or customize. The .NET modernization transformation includes 50,000 free agent minutes per month. Read more

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts and resources that you might find interesting:

  • Clare Liguori on frontier engineering – If you already use an AI coding assistant but don’t feel like you’re shipping much faster, start here. Clare Liguori, Senior Principal Engineer at AWS, published a practitioner’s manifesto on frontier engineering: ten principles, drawn from teams across Amazon, for changing how you build software with AI agents. The argument is direct. Software development has split in two, people who changed how they work with agents, and people who only changed their coding tools. Frontier engineering is not vibe coding. You spend the first weeks writing steering files, refactoring the codebase, and learning to decompose work for agents. Those weeks feel slower. The weeks after feel dramatically faster, because you’re no longer building the software directly — you’re building the agent setup that builds the software.
  • A free year of Kiro for students around the world – The Kiro Students program is expanding from 11 universities to 121 new schools across 16 countries. Eligible students get one year of Kiro with 1,000 credits per month and full access to paid features such as premium models and Kiro Web, no credit card and no trial timer. You can work in the IDE, the CLI, Kiro Web in a browser, or Kiro Crew. If you’re a student, sign up with your university email.
  • The state of AI for security: measuring what matters for trust – Security teams are using AI for triage, threat modeling, incident response, and code review, but a tool that flags everything doesn’t save time. In The state of AI for security, Anshumali Shrivastava and Neha Rungta introduce Deception Benchmark, a new evaluation that tests whether a model can tell a real vulnerability from code that looks risky but is actually safe. The benchmark includes 14,822 samples across 16 languages and more than 70 Common Weakness Enumeration (CWE) categories. Under standard prompting, precision landed in the mid-50s, about as likely to be inaccurate as accurate, and none of the 12 models tested kept both false positives and false negatives below 10 percent. The post links to the dataset, whitepaper, and submission workflow for verified scoring.
  • Build full-stack AWS applications in minutes with AI-powered scaffolding – Version 1.0 of the Nx Plugin for AWS is an open source toolkit of deterministic generators for APIs, websites, databases, and AI agents, plus the AWS infrastructure to run them. Each generator writes working, deployable code with security, observability, and type-safety already in place, so an AI assistant can assemble the foundation and spend its effort on your application logic. Bingo Industries used it to take a multi-agent operations chatbot from idea to production in less than 3 weeks. The plugin is open source on GitHub. Create a workspace with pnpm create @aws/nx-workspace and point your coding agent at the included MCP server.
  • The oldest architecture in computing – On All Things Distributed, Werner Vogels starts from a question customers always ask “Will AI take my job?”, and lands on memory. After spending time with Kiro Crew, he traces a line from Jeff Hawkins’ A Thousand Brains to how Crew stores, consolidates, and forgets across markdown files, a vector database, and a key-value index. His conclusion: the brain is the oldest architecture in computing, and the people who think hardest about how it works will build the next tools. Now, go build.

For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse here for upcoming AWS-led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Micah

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Scale down Kinesis Data Streams on-demand capacity with ODA warm throughput

Post Syndicated from Pratik Patel original https://aws.amazon.com/blogs/big-data/scale-down-kinesis-data-streams-on-demand-capacity-with-oda-warm-throughput/

Customers have been using Amazon Kinesis Data Streams to stream data at any scale. Some use On-demand Standard to let the service manage capacity, while others with predictable traffic patterns use On-demand Advantage and warm throughput to ensure streams can handle instant throughput increases. Streaming workloads rarely run at peak volume all the time: flash sales end, batch migrations complete, and telemetry bursts subside. However, manual intervention is often required to scale back down after the burst subsides. Amazon Kinesis Data Streams now supports scaling down ingest capacity for on-demand Advantage streams with warm throughput, which optimizes downstream compute costs and performance by removing excess capacity. You configure this by turning on On-demand Advantage mode (ODA) and setting a new warm throughput value that is equal to or smaller than the existing amount.

With this launch, you can now proactively reduce write throughput capacity, optimizing costs while maintaining performance and giving you more control over your stream’s provisioning.

In this post, we explore the warm throughput scale-down capability. We cover the challenge it addresses, how it works, how to monitor stream behavior with Amazon CloudWatch metrics, and best practices for using it effectively.

The challenge: Excess capacity after traffic spikes

Amazon Kinesis Data Streams on-demand mode automatically scales to handle increases in data throughput. When your stream experiences a traffic spike, Kinesis Data Streams splits shards to accommodate the higher volume. This automatic scaling helps your applications keep pace with data during surges.

However, many real-world workloads experience transient bursts that don’t represent sustained throughput needs. Consider a retail platform that processes a flash sale event, a healthcare system that ingests a large batch of patient records during a migration window, or an Internet of Things (IoT) fleet that transmits a high-volume firmware update telemetry burst. In each scenario, the stream scales up to accommodate the spike, but the elevated capacity remains long after the burst has subsided. Although Kinesis on-demand Advantage doesn’t charge for the elevated capacity, your consuming applications may see a higher cost and lower performance.

Consider a Kinesis data stream running with 100 MB/s ingest throughput that requires 100 shards. A traffic spike of an additional 50 MB/s forces on-demand mode to scale streams to 150 shards. The spike subsides within minutes, but those 150 shards remain.

If your AWS Lambda consumer uses a parallelization factor of 2, you go from 200 concurrent invocations (2 × 100 shards) to 300 (2 × 150 shards). This is a 50 percent jump in concurrent Lambda execution, even though ingest throughput has returned to 100 MB/s. Those extra 100 AWS Lambda invocations consume compute, count against your concurrent execution quota, and add cost while processing data with small batch sizes.

Kinesis Client Library (KCL) consumers incur operational overhead. KCL tracks one lease per shard in Amazon DynamoDB, so 50 additional shards mean 50 more leases to scan, renew, and checkpoint every heartbeat cycle. The result is more Amazon DynamoDB overhead for lease management and reduced consumption performance overall.

Before this launch, you had limited options to address this excess capacity:

  • Switch to provisioned mode to manually set shard count, losing the benefits of automatic scaling.
  • Accept the higher capacity and associated costs until the stream self-adjusted.

These approaches either introduced operational overhead or resulted in paying for capacity that exceeded your workload’s actual requirements.

The solution: Warm throughput scale-down

With on-demand capacity reduction, you can now set a lower or equal warm throughput value on your on-demand stream to trigger a capacity reduction. The stream adjusts to the requested capacity or the amount needed to support peak data ingest usage within the last hour, whichever is higher. This safeguard helps your stream retain sufficient capacity for current traffic while releasing the excess you no longer need.

This capability is available at no additional cost for all on-demand streams that have On-demand Advantage mode turned on.

How it works

Warm throughput provides bidirectional capacity management for on-demand streams:

  • Scale up (existing capability): If you forecast an upcoming traffic event, you can configure warm throughput to a higher value to prepare the stream in advance so that capacity is available when data arrives without throttling.
  • Scale down (new capability): If a transient burst has caused the stream to scale significantly beyond its steady-state needs, you can trigger a scale-down by setting warm throughput to a lower value.

When you set a warm throughput value that is equal to or lower than the current value on an on-demand stream, Kinesis Data Streams evaluates the request against your stream’s recent traffic. The resulting capacity is the greater of:

  1. The warm throughput value you requested.
  2. The capacity needed to support peak data ingest usage within the last hour.

This mechanism prevents you from accidentally reducing capacity below what your current workload demands. If data traffic increases after a scale-down has completed, on-demand mode can still expand stream ingest capacity through reactive scaling to avoid rate limiting.

Getting started

Prerequisites

To follow along, you need the following:

  1. An existing Kinesis data stream in on-demand mode.
  2. On-demand Advantage mode turned on.
  3. AWS Command Line Interface (AWS CLI) installed and configured.
  4. AWS Identity and Access Management (IAM) permissions for kinesis:UpdateStreamMode.

To trigger a scale-down, set a lower warm throughput value on your on-demand stream using the AWS CLI:

aws kinesis update-stream-mode \
--stream-arn arn:aws:kinesis:us-east-1:111122223333:stream/my-stream/my-stream \
--warm-throughput-in-mb 50

Monitoring stream behavior with Amazon CloudWatch

To observe the effects of a scale-down operation and understand your stream’s capacity and shard count, Amazon CloudWatch provides several key metrics. Monitoring these metrics helps you make informed decisions about when and how much to scale down.

Key metrics to monitor

The following table summarizes the CloudWatch metrics most relevant to warm throughput scale-down:

Metric Namespace Description
IncomingBytes AWS/Kinesis Total bytes ingested per period. Use the Sum statistic to see aggregate throughput across all shards.
IncomingRecords AWS/Kinesis Total records ingested per period. Helps identify traffic patterns and burst frequency.
WriteProvisionedThroughputExceeded AWS/Kinesis Number of records rejected because of throttling. A non-zero value after scale-down indicates capacity is set too low.

Observing shard count behavior during scale-down

To track shard count changes resulting from a scale-down, use the DescribeStreamSummary API, which returns the OpenShardCount field in its response. Note that OpenShardCount is not a CloudWatch metric. It’s available through the API and is also displayed on the Kinesis Data Streams console. You can poll this value periodically or build a custom CloudWatch metric using an AWS Lambda function to track shard count over time.

Here is how you can expect the stream to behave:

  1. Before the burst: Your stream operates at steady-state with a baseline shard count appropriate for your normal traffic. For example, a stream handling 20 MiB/s of write throughput might have approximately 67 open shards.
  2. During the burst: As traffic spikes, Kinesis Data Streams automatically splits shards to accommodate the increased load. The OpenShardCount rises, and IncomingBytes increases correspondingly.
  3. After the burst (before scale-down): Traffic returns to baseline, but the OpenShardCount remains elevated because the stream retains capacity for up to double the recently observed peak.
  4. After triggering scale-down: After you set a lower warm throughput, the OpenShardCount decreases as Kinesis Data Streams merges shards to match the requested capacity (subject to the one-hour peak safeguard). You can observe this transition by polling DescribeStreamSummary or on the Kinesis console.
Chart showing Kinesis Data Streams shard count rising during a traffic spike and decreasing after a warm throughput scale-down

Figure 1: Amazon Kinesis Data Streams shard count over time during a scale-down event, showing the incoming-data spike and the resulting change in shard count

Best practices

When using warm throughput scale-down, consider the following recommendations:

  1. Analyze traffic patterns before scaling down. Review at least 24 hours of IncomingBytes and IncomingRecords CloudWatch metrics to understand your baseline throughput before setting a lower warm throughput value. This helps you avoid setting capacity below your actual steady-state needs.
  2. Set warm throughput above your observed steady-state peak. Because on-demand streams accommodate up to double the observed peak, set your target warm throughput at or above your typical peak rather than your average. This maintains headroom for normal traffic variability without throttling.
  3. Monitor throttling after scale-down. Watch WriteProvisionedThroughputExceeded closely in the hours following a scale-down. If throttling occurs, increase the warm throughput value. The stream will automatically scale back up, but proactive monitoring reduces the duration of any impact.
  4. Use scale-down after known transient events. The feature is most effective when you can identify that a traffic spike was temporary, for example, after a planned batch migration, marketing event, or scheduled data backfill. Avoid scaling down during periods of uncertain or growing traffic.
  5. Use the one-hour safeguard. The system won’t reduce capacity below what’s needed to serve peak ingest from the last hour. If you’re unsure about the right target, you can set a low warm throughput value and rely on this safeguard to prevent under-provisioning for active traffic.

Conclusion

Amazon Kinesis Data Streams now supports scaling down ingest capacity with warm throughput, giving you elastic control over On-demand Advantage stream capacity. With this capability, you can release excess capacity after transient traffic bursts, improving cost efficiency while maintaining the automatic scaling benefits of on-demand mode.

To get started, turn on On-demand Advantage mode for your stream and use the warm throughput setting to manage capacity. Track shard count with DescribeStreamSummary to observe capacity changes and confirm your stream keeps appropriate headroom for your workload. Try warm throughput scale-down today in the Amazon Kinesis console, and to learn more, see Amazon Kinesis Data Streams on-demand capacity mode in the Developer Guide.


About the authors

Pratik Patel

Pratik Patel

Pratik is Sr Technical Account Manager and streaming analytics specialist. He works with AWS customers and provides ongoing support and technical guidance to help plan and build solutions using best practices and proactively helps in keeping customers’ AWS environments operationally healthy.

Priyanka Chaudhary

Priyanka Chaudhary

Priyanka is Senior Solutions Architect at AWS. She is specialized in data lake and analytics services and helps many customers in this area. As a Solutions Architect, she plays a crucial role in guiding strategic customers through their cloud journey by designing scalable and secure cloud solutions. Outside of work, she loves spending time with friends and family, watching movies, and traveling.

Varsha Palepu

Varsha Palepu

Varsha is a Solutions Architect and an analytics specialist on the AWS streaming team. She helps small and medium businesses innovate on AWS and creates technical streaming content to empower customers in their cloud journey.

The collective thoughts of the interwebz