SIKE Broken

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/08/sike-broken.html

SIKE is one of the new algorithms that NIST recently added to the post-quantum cryptography competition.

It was just broken, really badly.

We present an efficient key recovery attack on the Supersingular Isogeny Diffie­-Hellman protocol (SIDH), based on a “glue-and-split” theorem due to Kani. Our attack exploits the existence of a small non-scalar endomorphism on the starting curve, and it also relies on the auxiliary torsion point information that Alice and Bob share during the protocol. Our Magma implementation breaks the instantiation SIKEp434, which aims at security level 1 of the Post-Quantum Cryptography standardization process currently ran by NIST, in about one hour on a single core.

News article.

Astro Pi Mission Space Lab 2021/22: The Results

Post Syndicated from Sam Duffy original https://www.raspberrypi.org/blog/astro-pi-mission-space-lab-2021-22-the-results/

It’s been an incredible year for the European Astro Pi Challenge. We’ve sent new hardware into space, seen record numbers of young people participate in the Challenge, and received lots of fantastic programs. Before we say goodbye to the 2021/22 European Astro Pi Challenge, the Raspberry Pi Foundation and the European Space Agency are thrilled to announce this year’s winning and highly commended Mission Space Lab teams. 

What is Mission Space Lab?

In Mission Space Lab, teams of young people aged up to 19 work together to create scientific experiments to be carried out on the International Space Station. Their mission is to design and create a program to run on the two Astro Pi computers — space-adapted Raspberry Pis with cameras and a range of sensors.  

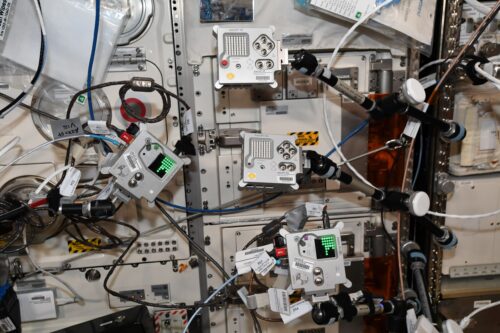
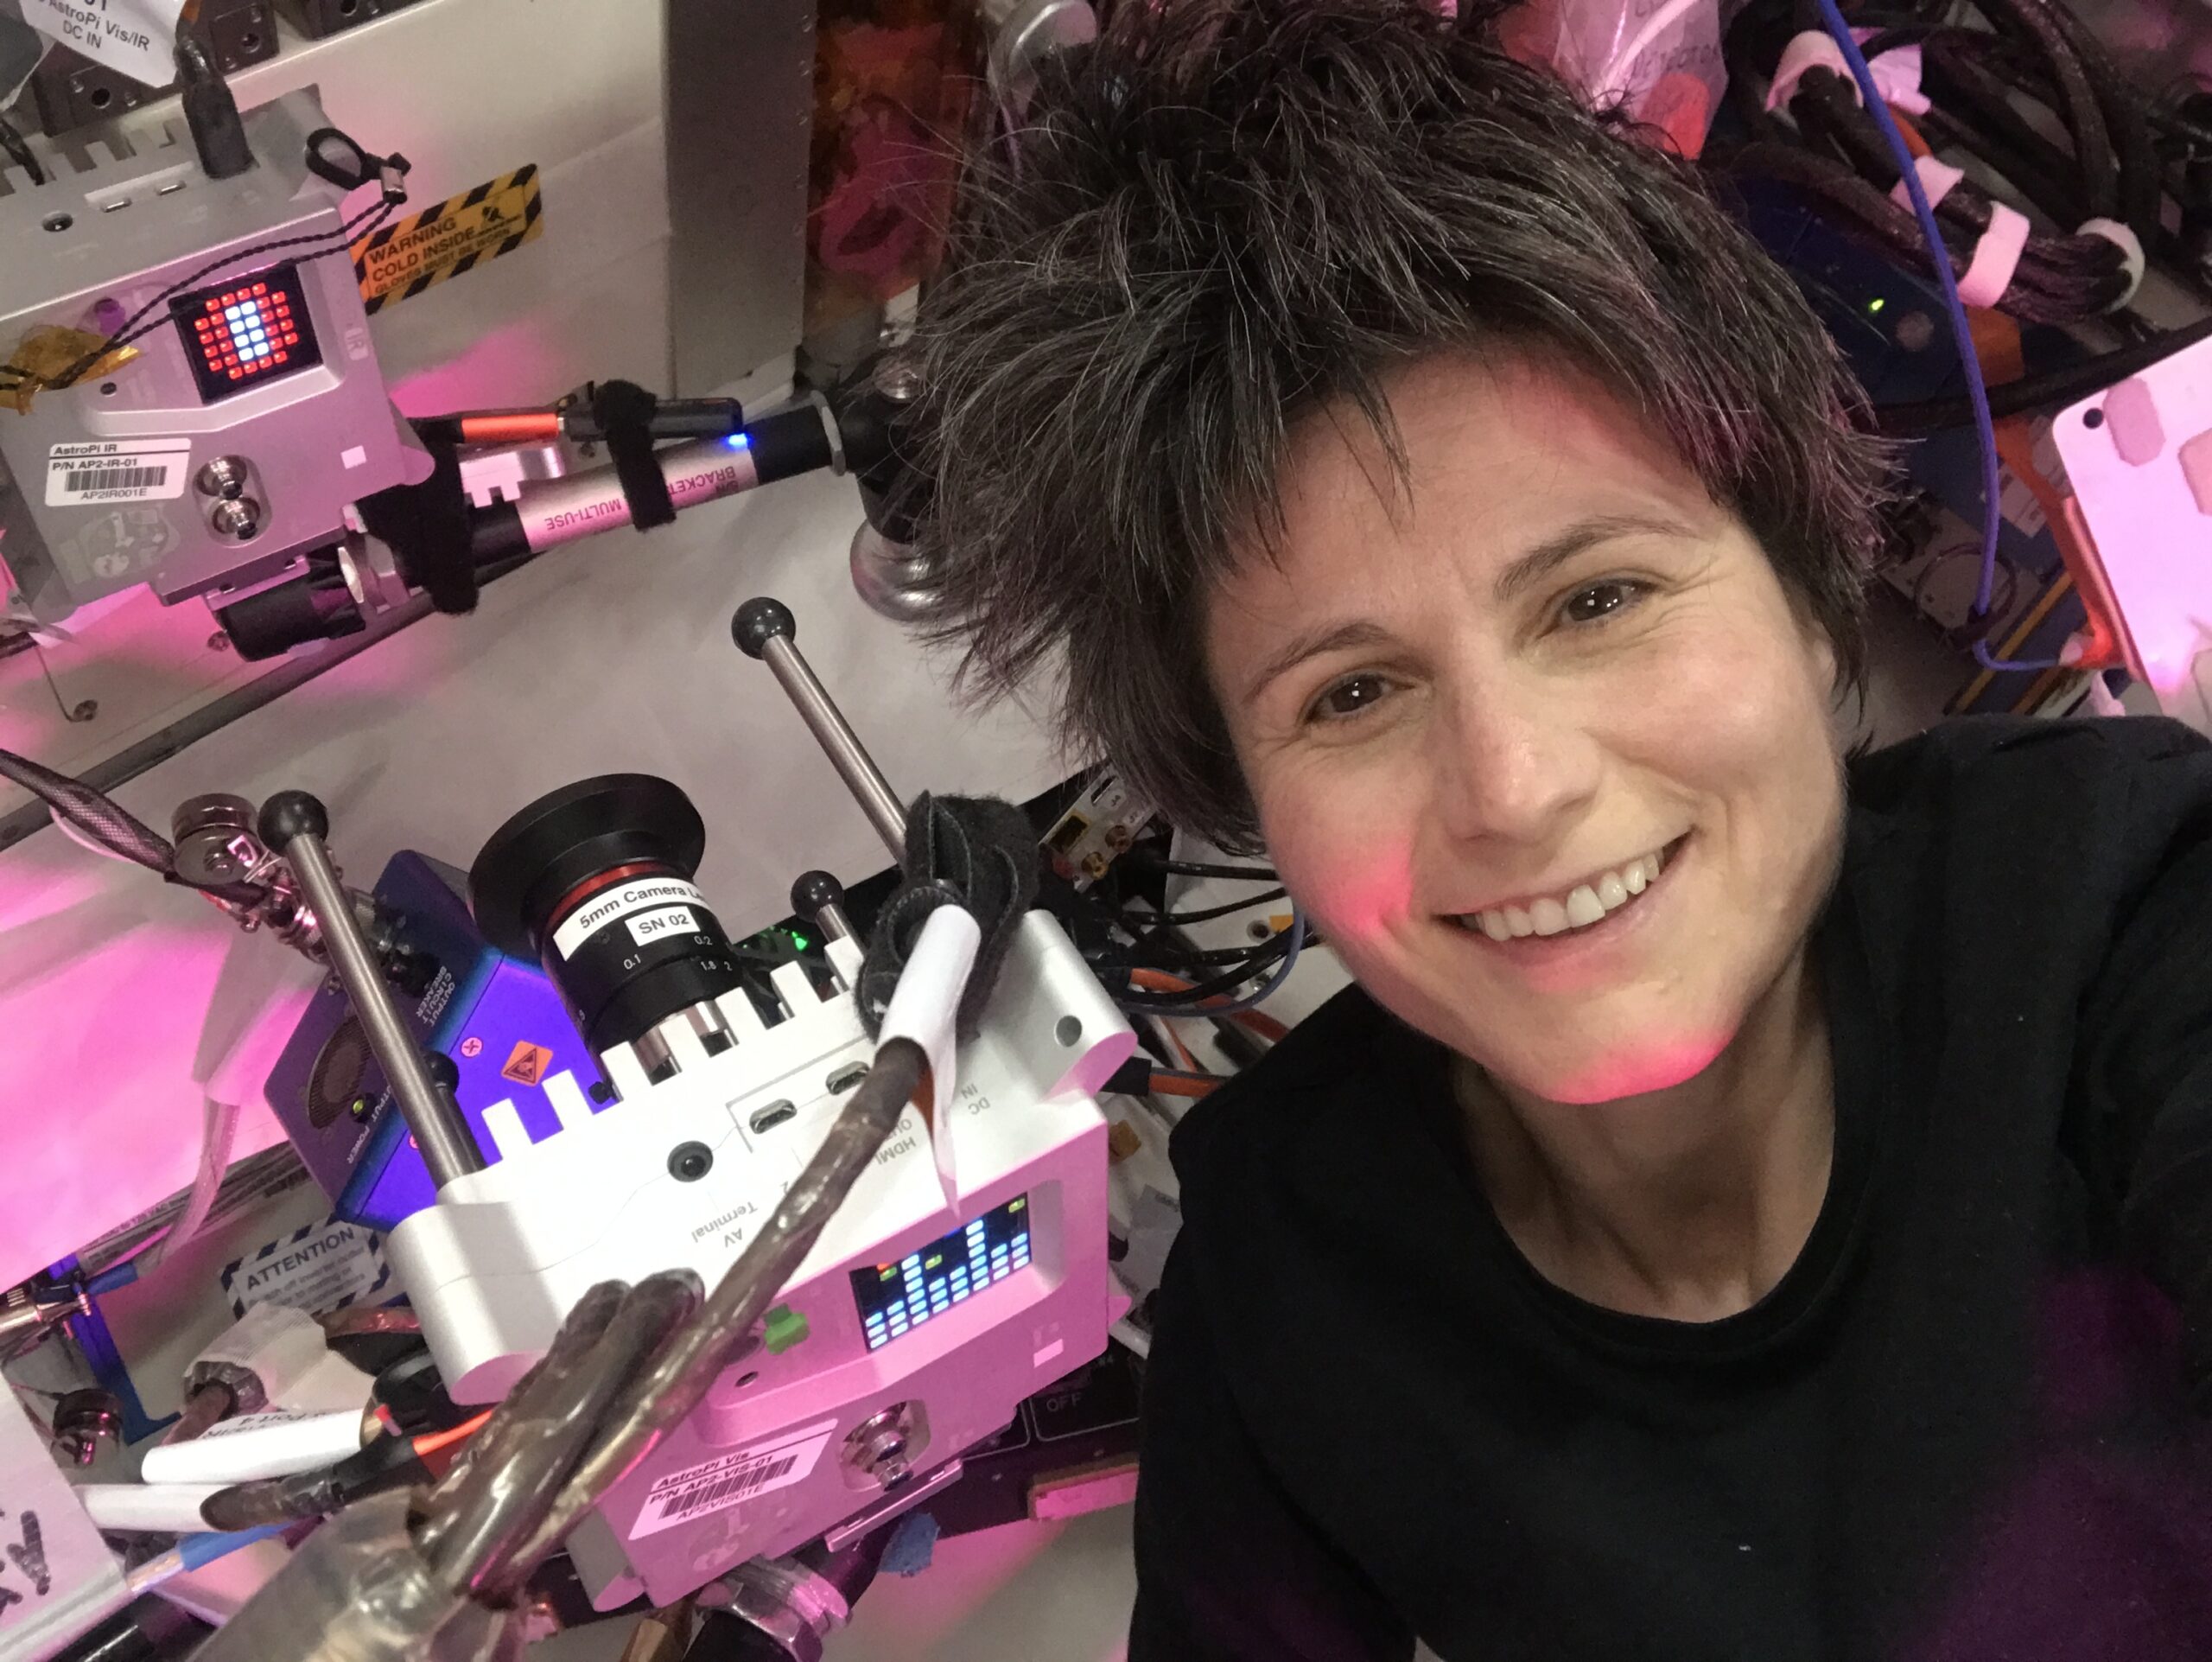
Samantha Cristoforetti.
ESA astronaut Samantha Cristoforetti with the new Astro Pi computers on the ISS
Credit: ESA/NASA

This year, 799 teams of young people designed experiments and entered Mission Space Lab and 502 of these teams were invited to Phase 2, which is 25% more than last year! The teams each received an Astro Pi kit to write and test their programs on and 299 teams submitted programs that passed rigorous testing at Astro Pi Mission Control and achieved ‘flight status’.

After their program collected data during the experiment’s three-hour runtime on the ISS, each team analysed the results and wrote a short report to describe their experiment.  

We were especially excited to see what experiments young people would investigate this year, as their programs would be the first to run on the brand-new Astro Pi units, which were named after Nikola Tesla and Marie Curie by participants in this year’s Mission Zero.

Astro Pi computers on the ISS.
The two original Astro Pis with the new upgraded Astro Pis, together on the ISS
Credit: ESA/NASA

Let’s take a look at the teams’ investigations for Mission Space Lab 2021/22!

Clouds, volcanos, and seaweed rafts

In this year’s Challenge, the environment and climate change was a strong theme among the 205 team experiment reports. Several teams investigated topics such as changing water levels, wildfires, and the effect of different clouds and aeroplane contrails on global warming. 

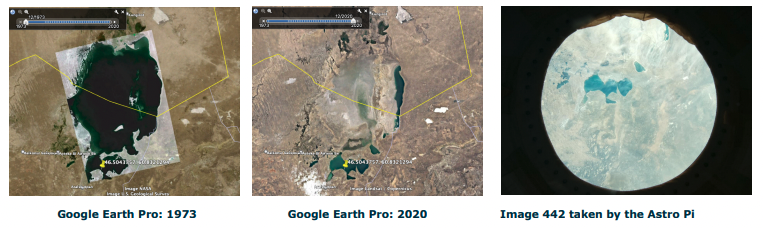
Team Seekers from Itis Delpozzo Cuneo in Italy and Team Adastra from St Paul’s Girls’ School in the UK made observations about reduction of water levels in the Aral Sea, located between Kazakhstan and Uzbekistan.

The Aral Sea photographed from the ISS by team Adastra.
Team Adastra compared their image of the Aral Sea with data from Google Earth to show the significant decrease in water coverage

“We have gained skills with data research and machine learning, in relation to scientific experiments, which will hopefully give us a basis to move into more complex projects with machine learning.”

Team Adastra

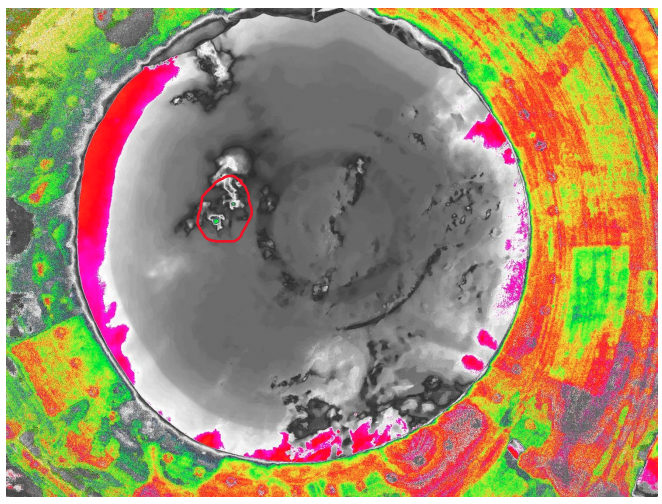
Team St Marks from Saint Marks Church of England School in the UK calculated NDVI (normalised difference vegetation index) for images they had captured to look for macroplastics in the ocean. This is a technique for identifying vegetation from images. The team used it to search for the rafts of sargassum seaweed that form around plastics floating on the water. They were lucky enough to successfully photograph and identify several seaweed rafts during their three hour experiment time. 

Seaweed rafts photographed on the ISS by team St Marks.
Two seaweed rafts (circled in red) off the coast of Brazil captured by Team St Marks

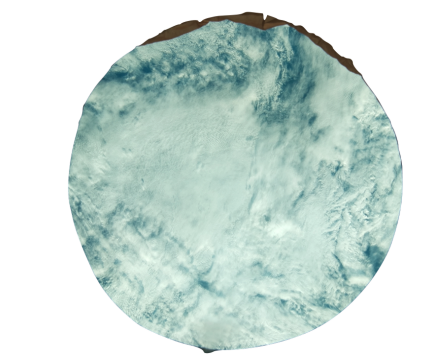
Team Nanokids from the UK used the Coral machine learning accelerator to analyse images of clouds in real time. Collecting this data could be used to warn aircraft of the risk of turbulence, predict weather, and detect pollution. The team reported that they “learned a lot about the various different cloud types, their characteristics and their different effects, as well as how to create a simple ML model with Teachable Machine, which will help us in future projects.”

Cumulonimbus cloud photographed on the ISS by team Nanokids.
Cumulonimbus cloud analysed by Team Nanokids

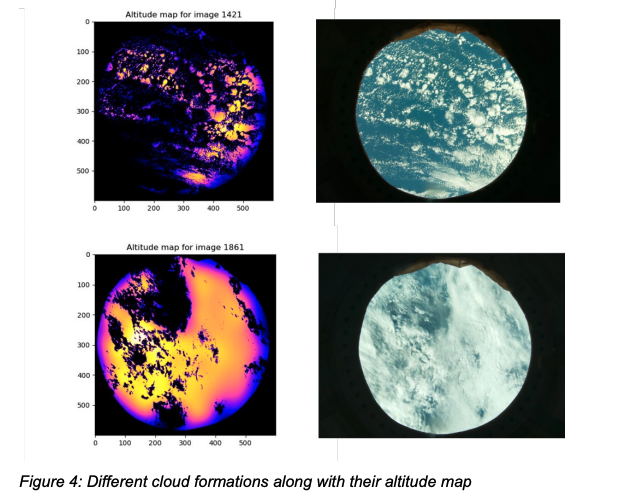
Team Centauri from Diverbot in Spain were inspired by the influence of high altitude cloud vapour on the Greenhouse Effect to calculate the height of clouds from images taken by the Raspberry Pi High Quality Camera. They identified the potential to scale-up their experiment, in order to analyse hundreds or thousands of images of clouds and calculate their impact on the temperature of the Earth. 

Cloud formations photographed on the ISS by team Centauri.
Some examples of the cloud formations analysed by Team Centauri

We also saw lots of experiment reports about volcanoes. Team Six Sense from Escola Secundária Inês de Castro in Portugal ran an experiment inspired by the La Palma volcano, which erupted in September 2021. The team’s experiment captured images of a volcano in Fogo Island, Cape Verde. 

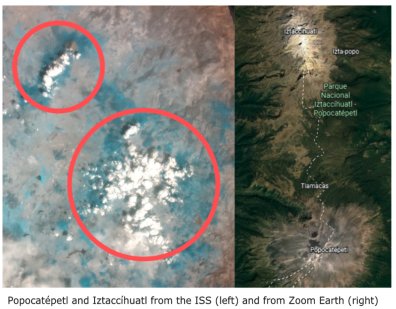
Team LandISS from Liceo Scientifico “A. Landi” in Italy captured an extraordinary image of emissions from the Popocatépetl volcano in Mexico, which reactivated in 1994 and has been producing powerful explosions at irregular intervals ever since.

Popocatépetl Volcano photographed from the ISS by team LandISS.
Popocatépetl volcano in the Iztaccíhuatl–Popocatépetl National Park by Team LandISS

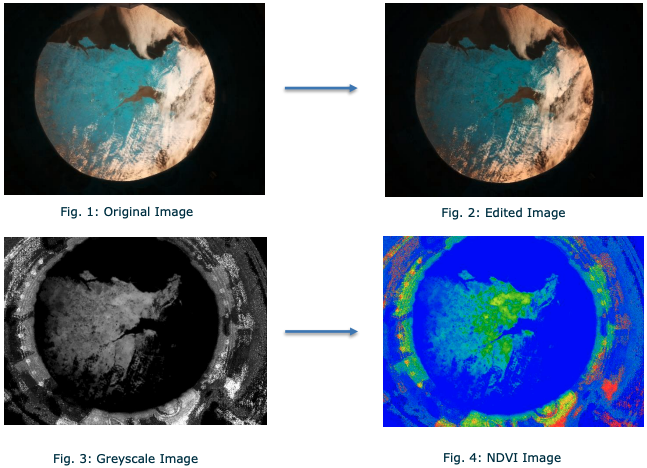
Team DuoDo from Liceul Teoretic Tudor Vianu in Romania investigated if there had been changes to vegetation health on the Earth since the pandemic, by comparing NDVI calculations from their data. The judges were especially impressed with how they reported their analysis and results.

NDVI processing by team DoDuo.
NDVI processing by Team DoDuo

Team Atlantes from Niubit in Spain wanted to build a bridge between the real and virtual world by visualising their NDVI calculations as a three dimensional Minecraft video game. Check out how they did this and some of their results in their video.

From ISS 🛰️ to Minecraft 🧱 : Astro Pi Mission Space Lab 2021-22 by Team Atlantes

Team Rocha21, from IES José Frugoni Pérez in the Canary Islands, also explored different ways to communicate and share their data. They used sonoUno (software originally developed to sonify astronomical data) and online Braille translators to design tactile diagrams in order to explore their Life on Earth photographs and NDVI data, working in collaboration with six visually-impaired students.

Up in space

Some of this year’s Mission Space Lab teams chose to conduct their experiments about life on the ISS. We saw experiments to investigate the possibility for growing fungi as space crops (Team NGC224 from CoderDojo Perugia in Italy) and the effect of temperature and pressure on the human body on Earth and in space (Team CDV-CDI2 from CoderDojo Votanikos in Greece, in collaboration with CoderDojo Iraq).

Team Hyperion from JVS Hyperion in Belgium investigated the effect of the sun on the Earth’s magnetic field, comparing data collected during daytime and nighttime as the ISS orbited Earth.

Not only did we get to see this year’s experiments, but we also had a chance to hear them! Sound and music was very popular among the Mission Space Lab teams. 

Team Cuza3 from Colegiul National ”Alexandru Ioan Cuza” in Romania, made “The Ballad of Pressure” by attributing notes to pressure data from the ISS. Team Alessi Pi from Liceo Scientifico “G.Alessi” in Italy made a melody by mapping data to a music scale with other sensor readings mapped to additional instruments. 

Team Gubbins, from Hyvinkään Lukio in Finland, measured magnetic flux density to determine the strength of the Earth’s magnetic field, using the Astro Pi magnetometer, which they sonified and used to make a music video. 

Sonification of the Earth’s magnetic field by Team Gubbins

And the winning teams are…

The judges from ESA and the Raspberry Pi Foundation took on the huge task of reviewing all the reports to consider scientific merit, experiment design and methodology, data analysis, report quality, and innovative use of the Astro Pi hardware. 

The ten winning teams come from coding clubs and schools from France, Italy, Greece, Spain, Romania, and the United Kingdom and will each receive cool space swag. 

Winning teams

Team Project Organisation Country
AdAstra Life on Earth St Paul’s Girls’ School United Kingdom
Asterix Life on Earth Household France
Atlantes Life on Earth Niubit Spain
BetFrac Life on Earth Escoles Betlem Spain
Centauri Life on Earth Diverbot Spain
DoDuo Life on Earth Liceul Teoretic Tudor Vianu Romania
DSpi Life on Earth PEKTPE Grevenon Greece
GreenPi Life in Space IESS European High School Italy
NanoKids Life on Earth Household United Kingdom
RedsTeam Life in Space Household Italy

Highly commended teams

Team Project Organisation Country
CDV-CDI Life on Earth CoderDojo Votanikos and
CoderDojo Iraq
Greece
CorMat Life on Earth Sint-Jan Berchmanscollege Belgium
ISF Life in Space Luxembourg Tech School Luxembourg
LAZOS22 Life on Earth Aux Lazaristes La Salle France
Pithons Life on Earth The Perse School United Kingdom
Rocha21 Life on Earth IES José Frugoni Pérez Spain

Click each team name to read their experiment report. 

Every Astro Pi team that reached Phase 3 of Mission Space Lab will receive a certificate signed by ESA astronaut Samantha Cristoforetti to show family and friends that they have had a scientific experiment run on the ISS! 

The winning and highly commended teams will be invited to an online Q&A with an ESA astronaut in the autumn. Look out for more information about this soon!  

Congratulations Mission Space Lab teams 2021/22

Everyone from the Raspberry Pi Foundation and ESA Education teams congratulates this year’s Mission Space Lab participants — we hope you found it as fun and inspiring as we did! 

Thank you to everyone who has been involved in Mission Zero and Mission Space Lab as part of this year’s Challenge. It has been incredible to have 28,126 young people from 26 countries run their programs in space! We can’t wait to do it all again. 

When will the 2022/23 European Astro Pi Challenge lift off?

Mission Zero and Mission Space Lab relaunch in September 2022!

If you know a young person who would be interested in the Challenge, sign up for the newsletter on astro-pi.org and follow the Astro Pi Twitter account for all the latest announcements.

""

The post Astro Pi Mission Space Lab 2021/22: The Results appeared first on Raspberry Pi.

Graviton Fast Start – A New Program to Help Move Your Workloads to AWS Graviton

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/graviton-fast-start-a-new-program-to-help-move-your-workloads-to-aws-graviton/

With the Graviton Challenge last year, we helped customers migrate to Graviton-based EC2 instances and get up to 40 percent price performance benefit in as little as 4 days. Tens of thousands of customers, including 48 of the top 50 Amazon Elastic Compute Cloud (Amazon EC2) customers, use AWS Graviton processors for their workloads. In addition to EC2, many AWS managed services can run their workloads on Graviton. For most customers, adoption is easy, requiring minimal code changes. However, the effort and time required to move workloads to Graviton depends on a few factors including your software development environment and the technology stack on which your application is built.

This year, we want to take it a step further and make it even easier for customers to adopt Graviton not only through EC2, but also through managed services. Today, we are launching AWS Graviton Fast Start, a new program that makes it even easier to move your workloads to AWS Graviton by providing step-by-step directions for EC2 and other managed services that support the Graviton platform:

  • Amazon Elastic Compute Cloud (Amazon EC2) – EC2 provides the most flexible environment for a migration and can support many kinds of workloads, such as web apps, custom databases, or analytics. You have full control over the interpreted or compiled code running in the EC2 instance. You can also use many open-source and commercial software products that support the Arm64 architecture.
  • AWS Lambda – Migrating your serverless functions can be really easy, especially if you use an interpreted runtime such as Node.js or Python. Most of the time, you only have to check the compatibility of your software dependencies. I have shown a few examples in this blog post.
  • AWS Fargate – Fargate works best if your applications are already running in containers or if you are planning to containerize them. By using multi-architecture container images or images that have Arm64 in their image manifest, you get the serverless benefits of Fargate and the price-performance advantages of Graviton.
  • Amazon Aurora – Relational databases are at the core of many applications. If you need a database compatible with PostgreSQL or MySQL, you can use Amazon Aurora to have a highly performant and globally available database powered by Graviton.
  • Amazon Relational Database Service (RDS) – Similarly to Aurora, Amazon RDS engines such as PostgreSQL, MySQL, and MariaDB can provide a fully managed relational database service using Graviton-based instances.
  • Amazon ElastiCache – When your workload requires ultra-low latency and high throughput, you can speed up your applications with ElastiCache and have a fully managed in-memory cache running on Graviton and compatible with Redis or Memcached.
  • Amazon EMR – With Amazon EMR, you can run large-scale distributed data processing jobs, interactive SQL queries, and machine learning applications on Graviton using open-source analytics frameworks such as Apache Spark, Apache Hive, and Presto.

Here’s some feedback we got from customers running their workloads on Graviton:

  • Formula 1 racing told us that Graviton2-based C6gn instances provided the best price performance benefits for some of their computational fluid dynamics (CFD) workloads. More recently, they found that Graviton3 C7g instances are 40 percent faster for the same simulations and expect Graviton3-based instances to become the optimal choice to run all of their CFD workloads.
  • Honeycomb has 100 percent of their production workloads running on Graviton using EC2 and Lambda. They have tested the high-throughput telemetry ingestion workload they use for their observability platform against early preview instances of Graviton3 and have seen a 35 percent performance increase for their workload over Graviton2. They were able to run 30 percent fewer instances of C7g than C6g serving the same workload and with 30 percent reduced latency. With these instances in production, they expect over 50 percent price performance improvement over x86 instances.
  • Twitter is working on a multi-year project to leverage Graviton-based EC2 instances to deliver Twitter timelines. As part of their ongoing effort to drive further efficiencies, they tested the new Graviton3-based C7g instances. Across a number of benchmarks representative of their workloads, they found Graviton3-based C7g instances deliver 20-80 percent higher performance compared to Graviton2-based C6g instances, while also reducing tail latencies by as much as 35 percent. They are excited to utilize Graviton3-based instances in the future to realize significant price performance benefits.

With all these options, getting the benefits of running all or part of your workload on AWS Graviton can be easier than you expect. To help you get started, there’s also a free trial on the Graviton-based T4g instances for up to 750 hours per month through December 31st, 2022.

Visit AWS Graviton Fast Start to get step-by-step directions on how to move your workloads to AWS Graviton.

— Danilo

[$] Oaxaca, Endless OS, and indigenous languages

Post Syndicated from original https://lwn.net/Articles/903597/

A rural Mexican state was the setting for an initiative to use
the GNOME-based Endless OS to
improve
education in indigenous
communities. Over the last several
years, the Endless OS Foundation
has teamed up with the Fundación Alfredo Harp
Helú Oaxaca
(FAHHO) to deliver offline-first computers to those
communities, but also to assist these communities in preserving their native
languages. In a talk at GUADEC 2022, Rob McQueen
provided a look at the project and what it has accomplished.

[Security Nation] Curt Barnard on Defaultinator (Black Hat Arsenal Preview)

Post Syndicated from Rapid7 original https://blog.rapid7.com/2022/08/03/security-nation-curt-barnard-on-defaultinator-black-hat-arsenal-preview/


[Security Nation] Curt Barnard on Defaultinator (Black Hat Arsenal Preview)

In this episode of Security Nation, Jen and Tod chat with Curt Barnard, Principal Security Researcher at Rapid7, about a new tool he’ll be presenting at Black Hat Arsenal, the showcase of open-source tools at Black Hat 2022 in Las Vegas. Curt gives us the details about the tool, Defaultinator, which helps security pros look up and audit for default credentials more quickly and effectively. He also tells us what else he’s excited about at this year’s lineup of cybersecurity conferences in Vegas next week.

Stick around for our Rapid Rundown, where Tod and Jen talk about a Rapid7 alum’s discovery of a vulnerability in DSL- and fiber-based web routers from Arris, as well as a recent article that debates the benefits of sharing exploit proofs of concept versus keeping them private.

Curt Barnard

[Security Nation] Curt Barnard on Defaultinator (Black Hat Arsenal Preview)

Curt Barnard is a cybersecurity professional with 15 years of experience across both the public and private sector. At Rapid7, Curt is a Principal Security Researcher working with projects Sonar and Heisenberg, analyzing internet-wide security issues with global impact. Before joining the team at Rapid7, Curt spent time breaking software with the Department of Defense, vetting cybersecurity companies for venture capital firms, and building his own startup from the ground up. When he isn’t busy popping calc.exe, Curt enjoys changing your desktop’s wallpaper and moving your icons around.

Show notes

Interview links

Rapid Rundown links

Like the show? Want to keep Jen and Tod in the podcasting business? Feel free to rate and review with your favorite podcast purveyor, like Apple Podcasts.

Want More Inspiring Stories From the Security Community?

Subscribe to Security Nation Today

Best practices to optimize cost and performance for AWS Glue streaming ETL jobs

Post Syndicated from Gonzalo Herreros original https://aws.amazon.com/blogs/big-data/best-practices-to-optimize-cost-and-performance-for-aws-glue-streaming-etl-jobs/

AWS Glue streaming extract, transform, and load (ETL) jobs allow you to process and enrich vast amounts of incoming data from systems such as Amazon Kinesis Data Streams, Amazon Managed Streaming for Apache Kafka (Amazon MSK), or any other Apache Kafka cluster. It uses the Spark Structured Streaming framework to perform data processing in near-real time.

This post covers use cases where data needs to be efficiently processed, delivered, and possibly actioned in a limited amount of time. This can cover a wide range of cases, such as log processing and alarming, continuous data ingestion and enrichment, data validation, internet of things, machine learning (ML), and more.

We discuss the following topics:

  • Development tools that help you code faster using our newly launched AWS Glue Studio notebooks
  • How to monitor and tune your streaming jobs
  • Best practices for sizing and scaling your AWS Glue cluster, using our newly launched features like auto scaling and the small worker type G 0.25X

Development tools

AWS Glue Studio notebooks can speed up the development of your streaming job by allowing data engineers to work using an interactive notebook and test code changes to get quick feedback—from business logic coding to testing configuration changes—as part of tuning.

Before you run any code in the notebook (which would start the session), you need to set some important configurations.

The magic %streaming creates the session cluster using the same runtime as AWS Glue streaming jobs. This way, you interactively develop and test your code using the same runtime that you use later in the production job.

Additionally, configure Spark UI logs, which will be very useful for monitoring and tuning the job.

See the following configuration:

%streaming
%%configure
{
"--enable-spark-ui": "true",
"--spark-event-logs-path": "s3://your_bucket/sparkui/"
}

For additional configuration options such as version or number of workers, refer to Configuring AWS Glue interactive sessions for Jupyter and AWS Glue Studio notebooks.

To visualize the Spark UI logs, you need a Spark history server. If you don’t have one already, refer to Launching the Spark History Server for deployment instructions.

Structured Streaming is based on streaming DataFrames, which represent micro-batches of messages.
The following code is an example of creating a stream DataFrame using Amazon Kinesis as the source:

kinesis_options = {
  "streamARN": "arn:aws:kinesis:us-east-2:777788889999:stream/fromOptionsStream",
  "startingPosition": "TRIM_HORIZON",
  "inferSchema": "true",
  "classification": "json"
}
kinesisDF = glueContext.create_data_frame_from_options(
   connection_type="kinesis",
   connection_options=kinesis_options
)

The AWS Glue API helps you create the DataFrame by doing schema detection and auto decompression, depending on the format. You can also build it yourself using the Spark API directly:

kinesisDF = spark.readStream.format("kinesis").options(**kinesis_options).load()

After your run any code cell, it triggers the startup of the session, and the application soon appears in the history server as an incomplete app (at the bottom of the page there is a link to display incomplete apps) named GlueReplApp, because it’s a session cluster. For a regular job, it’s listed with the job name given when it was created.

History server home page

From the notebook, you can take a sample of the streaming data. This can help development and give an indication of the type and size of the streaming messages, which might impact performance.

Monitor the cluster with Structured Streaming

The best way to monitor and tune your AWS Glue streaming job is using the Spark UI; it gives you the overall streaming job trends on the Structured Streaming tab and the details of each individual micro-batch processing job.

Overall view of the streaming job

On the Structured Streaming tab, you can see a summary of the streams running in the cluster, as in the following example.

Normally there is just one streaming query, representing a streaming ETL. If you start multiple in parallel, it’s good if you give it a recognizable name, calling queryName() if you use the writeStream API directly on the DataFrame.

After a good number of batches are complete (such as 10), enough for the averages to stabilize, you can use Avg Input/sec column to monitor how many events or messages the job is processing. This can be confusing because the column to the right, Avg Process/sec, is similar but often has a higher number. The difference is that this process time tells us how efficient our code is, whereas the average input tells us how many messages the cluster is reading and processing.

The important thing to note is that if the two values are similar, it means the job is working at maximum capacity. It’s making the best use of the hardware but it likely won’t be able to cope with an increase in volume without causing delays.

In the last column is the latest batch number. Because they’re numbered incrementally from zero, this tells us how many batches the query has processed so far.

When you choose the link in the “Run ID” column of a streaming query, you can review the details with graphs and histograms, as in the following example.

The first two rows correspond to the data that is used to calculate the averages shown on the summary page.

For Input Rate, each data point is calculated by dividing the number of events read for the batch by the time passed between the current batch start and the previous batch start. In a healthy system that is able to keep up, this is equal to the configured trigger interval (in the GlueContext.forEachBatch() API, this is set using the option windowSize).

Because it uses the current batch rows with the previous batch latency, this graph is often unstable in the first batches until the Batch Duration (the last line graph) stabilizes.

In this example, when it stabilizes, it gets completely flat. This means that either the influx of messages is constant or the job is hitting the limit per batch set (we discuss how to do this later in the post).

Be careful if you set a limit per batch that is constantly hit, you could be silently building a backlog, but everything could look good in the job metrics. To monitor this, have a metric of latency measuring the difference between the message timestamp when it gets created and the time it’s processed.

Process Rate is calculated by dividing the number of messages in a batch by the time it took to process that batch. For instance, if the batch contains 1,000 messages, and the trigger interval is 10 seconds but the batch only needed 5 seconds to process it, the process rate would be 1000/5 = 200 msg/sec. while the input rate for that batch (assuming the previous batch also ran within the interval) is 1000/10 = 100 msg/sec.

This metric is useful to measure how efficient our code processing the batch is, and therefore it can get higher than the input rate (this doesn’t mean it’s processing more messages, just using less time). As mentioned earlier, if both metrics get close, it means the batch duration is close to the interval and therefore additional traffic is likely to start causing batch trigger delays (because the previous batch is still running) and increase latency.

Later in this post, we show how auto scaling can help prevent this situation.

Input Rows shows the number of messages read for each batch, like input rate, but using volume instead of rate.

It’s important to note that if the batch processes the data multiple times (for example, writing to multiple destinations), the messages are counted multiple times. If the rates are greater than the expected, this could be the reason. In general, to avoid reading messages multiple times, you should cache the batch while processing it, which is the default when you use the GlueContext.forEachBatch() API.

The last two rows tell us how long it takes to process each batch and how is that time spent. It’s normal to see the first batches take much longer until the system warms up and stabilizes.
The important thing to look for is that the durations are roughly stable and well under the configured trigger interval. If that’s not the case, the next batch gets delayed and could start a compounding delay by building a backlog or increasing batch size (if the limit allows taking the extra messages pending).

In Operation Duration, the majority of time should be spent on addBatch (the mustard color), which is the actual work. The rest are fixed overhead, therefore the smaller the batch process, the more percentage of time that will take. This represents the trade-off between small batches with lower latency or bigger batches but more computing efficient.

Also, it’s normal for the first batch to spend significant time in the latestOffset (the brown bar), locating the point at which it needs to start processing when there is no checkpoint.

The following query statistics show another example.

In this case, the input has some variation (meaning it’s not hitting the batch limit). Also, the process rate is roughly the same as the input rate. This tells us the system is at max capacity and struggling to keep up. By comparing the input rows and input rate, we can guess that the interval configured is just 3 seconds and the batch duration is barely able to meet that latency.

Finally, in Operation Duration, you can observe that because the batches are so frequent, a significant amount of time (proportionally speaking) is spent saving the checkpoint (the dark green bar).

With this information, we can probably improve the stability of the job by increasing the trigger interval to 5 seconds or more. This way, it checkpoints less often and has more time to process data, which might be enough to get batch duration consistently under the interval. The trade-off is that the latency between when a message is published and when it’s processed is longer.

Monitor individual batch processing

On the Jobs tab, you can see how long each batch is taking and dig into the different steps the processing involves to understand how the time is spent. You can also check if there are tasks that succeed after retry. If this happens continuously, it can silently hurt performance.

For instance, the following screenshot shows the batches on the Jobs tab of the Spark UI of our streaming job.

Each batch is considered a job by Spark (don’t confuse the job ID with the batch number; they only match if there is no other action). The job group is the streaming query ID (this is important only when running multiple queries).

The streaming job in this example has a single stage with 100 partitions. Both batches processed them successfully, so the stage is marked as succeeded and all the tasks completed (100/100 in the progress bar).

However, there is a difference in the first batch: there were 20 task failures. You know all the failed tasks succeeded in the retries, otherwise the stage would have been marked as failed. For the stage to fail, the same task would have to fail four times (or as configured by spark.task.maxFailures).

If the stage fails, the batch fails as well and possibly the whole job; if the job was started by using GlueContext.forEachBatch(), it has a number of retries as per the batchMaxRetries parameter (three by default).

These failures are important because they have two effects:

  • They can silently cause delays in the batch processing, depending on how long it took to fail and retry.
  • They can cause records to be sent multiple times if the failure is in the last stage of the batch, depending on the type of output. If the output is files, in general it won’t cause duplicates. However, if the destination is Amazon DynamoDB, JDBC, Amazon OpenSearch Service, or another output that uses batching, it’s possible that some part of the output has already been sent. If you can’t tolerate any duplicates, the destination system should handle this (for example, being idempotent).

Choosing the description link takes you to the Stages tab for that job. Here you can dig into the failure: What is the exception? Is it always in the same executor? Does it succeed on the first retry or took multiple?

Ideally, you want to identify these failures and solve them. For example, maybe the destination system is throttling us because doesn’t have enough provisioned capacity, or a larger timeout is needed. Otherwise, you should at least monitor it and decide if it is systemic or sporadic.

Sizing and scaling

Defining how to split the data is a key element in any distributed system to run and scale efficiently. The design decisions on the messaging system will have a strong influence on how the streaming job will perform and scale, and thereby affect the job parallelism.

In the case of AWS Glue Streaming, this division of work is based on Apache Spark partitions, which define how to split the work so it can be processed in parallel. Each time the job reads a batch from the source, it divides the incoming data into Spark partitions.

For Apache Kafka, each topic partition becomes a Spark partition; similarly, for Kinesis, each stream shard becomes a Spark partition. To simplify, I’ll refer to this parallelism level as number of partitions, meaning Spark partitions that will be determined by the input Kafka partitions or Kinesis shards on a one-to-one basis.

The goal is to have enough parallelism and capacity to process each batch of data in less time than the configured batch interval and therefore be able to keep up. For instance, with a batch interval of 60 seconds, the job lets 60 seconds of data build up and then processes that data. If that work takes more than 60 seconds, the next batch waits until the previous batch is complete before starting a new batch with the data that has built up since the previous batch started.

It’s a good practice to limit the amount of data to process in a single batch, instead of just taking everything that has been added since the last one. This helps make the job more stable and predictable during peak times. It allows you to test that the job can handle volume of data without issues (for example, memory or throttling).

To do so, specify a limit when defining the source stream DataFrame:

  • For Kinesis, specify the limit using kinesis.executor.maxFetchRecordsPerShard, and revise this number if the number of shards changes substantially. You might need to increase kinesis.executor.maxFetchTimeInMs as well, in order to allow more time to read the batch and make sure it’s not truncated.
  • For Kafka, set maxOffsetsPerTrigger, which divides that allowance equally between the number of partitions.

The following is an example of setting this config for Kafka (for Kinesis, it’s equivalent but using Kinesis properties):

kafka_properties= {
  "kafka.bootstrap.servers": "bootstrapserver1:9092",
  "subscribe": "mytopic",
  "startingOffsets": "latest",
  "maxOffsetsPerTrigger": "5000000"
}
# Pass the properties as options when creating the DataFrame
spark.spark.readStream.format("kafka").options(**kafka_properties).load()

Initial benchmark

If the events can be processed individually (no interdependency such as grouping), you can get a rough estimation of how many messages a single Spark core can handle by running with a single partition source (one Kafka partition or one Kinesis shard stream) with data preloaded into it and run batches with a limit and the minimum interval (1 second). This simulates a stress test with no downtime between batches.

For these repeated tests, clear the checkpoint directory, use a different one (for example, make it dynamic using the timestamp in the path), or just disable the checkpointing (if using the Spark API directly), so you can reuse the same data.
Leave a few batches to run (at least 10) to give time for the system and the metrics to stabilize.

Start with a small limit (using the limit configuration properties explained in the previous section) and do multiple reruns, increasing the value. Record the batch duration for that limit and the throughput input rate (because it’s a stress test, the process rate should be similar).

In general, larger batches tend to be more efficient up to a point. This is because the fixed overhead taken for each to checkpoint, plan, and coordinate the nodes is more significant if the batches are smaller and therefore more frequent.

Then pick your reference initial settings based on the requirements:

  • If a goal SLA is required, use the largest batch size whose batch duration is less than half the latency SLA. This is because in the worst case, a message that is stored just after a batch is triggered has to wait at least the interval and then the processing time (which should be less than the interval). When the system is keeping up, the latency in this worst case would be close to twice the interval, so aim for the batch duration to be less than half the target latency.
  • In the case where the throughput is the priority over latency, just pick the batch size that provides a higher average process rate and define an interval that allows some buffer over the observed batch duration.

Now you have an idea of the number of messages per core our ETL can handle and the latency. These numbers are idealistic because the system won’t scale perfectly linearly when you add more partitions and nodes. You can use the messages per core obtained to divide the total number of messages per second to process and get the minimum number of Spark partitions needed (each core handles one partition in parallel).

With this number of estimated Spark cores, calculate the number of nodes needed depending on the type and version, as summarized in the following table.

AWS Glue Version Worker Type vCores Spark Cores per Worker
2 G 1X 4 8
2 G 2X 8 16
3 G 0.25X 2 2
3 G 1X 4 4
3 G 2X 8 8

Using the newer version 3 is preferable because it includes more optimizations and features like auto scaling (which we discuss later). Regarding size, unless the job has some operation that is heavy on memory, it’s preferable to use the smaller instances so there aren’t so many cores competing for memory, disk, and network shared resources.

Spark cores are equivalent to threads; therefore, you can have more (or less) than the actual cores available in the instance. This doesn’t mean that having more Spark cores is going to necessarily be faster if they’re not backed by physical cores, it just means you have more parallelism competing for the same CPU.

Sizing the cluster when you control the input message system

This is the ideal case because you can optimize the performance and the efficiency as needed.

With the benchmark information you just gathered, you can define your initial AWS Glue cluster size and configure Kafka or Kinesis with the number of partitions or topics estimated, plus some buffer. Test this baseline setup and adjust as needed until the job can comfortably meet the total volume and required latency.

For instance, if we have determined that we need 32 cores to be well within the latency requirement for the volume of data to process, then we can create an AWS Glue 3.0 cluster with 9 G.1X nodes (a driver and 8 workers with 4 cores = 32) which reads from a Kinesis data stream with 32 shards.

Imagine that the volume of data in that stream doubles and we want to keep the latency requirements. To do so, we double the number of workers (16 + 1 driver = 17) and the number of shards on the stream (now 64). Remember this is just a reference and needs to be validated; in practice you might need more or less nodes depending on the cluster size, if the destination system can keep up, complexity of transformations, or other parameters.

Sizing the cluster when you don’t control the message system configuration

In this case, your options for tuning are much more limited.

Check if a cluster with the same number of Spark cores as existing partitions (determined by the message system) is able to keep up with the expected volume of data and latency, plus some allowance for peak times.

If that’s not the case, adding more nodes alone won’t help. You need to repartition the incoming data inside AWS Glue. This operation adds an overhead to redistribute the data internally, but it’s the only way the job can scale out in this scenario.

Let’s illustrate with an example. Imagine we have a Kinesis data stream with one shard that we don’t control, and there isn’t enough volume to justify asking the owner to increase the shards. In the cluster, significant computing for each message is needed; for each message, it runs heuristics and other ML techniques to take action depending on the calculations. After running some benchmarks, the calculations can be done promptly for the expected volume of messages using 8 cores working in parallel. By default, because there is only one shard, only one core will process all the messages sequentially.

To solve this scenario, we can provision an AWS Glue 3.0 cluster with 3 G 1X nodes to have 8 worker cores available. In the code repartition, the batch distributes the messages randomly (as evenly as possible) between them:

def batch_function(data_frame, batch_id):
    # Repartition so the udf is called in parallel for each partition
    data_frame.repartition(8).foreach(process_event_udf)

glueContext.forEachBatch(frame=streaming_df, batch_function=batch_function)

If the messaging system resizes the number of partitions or shards, the job picks up this change on the next batch. You might need to adjust the cluster capacity accordingly with the new data volume.

The streaming job is able to process more partitions than Spark cores are available, but might cause inefficiencies because the additional partitions will be queued and won’t start being processed until others finish. This might result in many nodes being idle while the remaining partitions finish and the next batch can be triggered.

When the messages have processing interdependencies

If the messages to be processed depend on other messages (either in the same or previous batches), that’s likely to be a limiting factor on the scalability. In that case, it might help to analyze a batch (job in Spark UI) to see where the time is spent and if there are imbalances by checking the task duration percentiles on the Stages tab (you can also reach this page by choosing a stage on the Jobs tab).

Auto scaling

Up to now, you have seen sizing methods to handle a stable stream of data with the occasional peak.
However, for variable incoming volumes of data, this isn’t cost-effective because you need to size for the worst-case scenario or accept higher latency at peak times.

This is where AWS Glue Streaming 3.0 auto scaling comes in. You can enable it for the job and define the maximum number of workers you want to allow (for example, using the number you have determined needed for the peak times).

The runtime monitors the trend of time spent on batch processing and compares it with the configured interval. Based on that, it makes a decision to increase or decrease the number of workers as needed, being more aggressive as the batch times get near or go over the allowed interval time.

The following screenshot is an example of a streaming job with auto scaling enabled.

Splitting workloads

You have seen how to scale a single job by adding nodes and partitioning the data as needed, which is enough on most cases. As the cluster grows, there is still a single driver and the nodes have to wait for the others to complete the batch before they can take additional work. If it reaches a point that increasing the cluster size is no longer effective, you might want to consider splitting the workload between separate jobs.

In the case of Kinesis, you need to divide the data into multiple streams, but for Apache Kafka, you can divide a topic into multiple jobs by assigning partitions to each one. To do so, instead of the usual subscribe or subscribePattern where the topics are listed, use the property assign to assign using JSON a subset of the topic partitions that the job will handle (for example, {"topic1": [0,1,2]}). At the time of this writing, it’s not possible to specify a range, so you need to list all the partitions, for instance building that list dynamically in the code.

Sizing down

For low volumes of traffic, AWS Glue Streaming has a special type of small node: G 0.25X, which provides two cores and 4 GB RAM for a quarter of the cost of a DPU, so it’s very cost-effective. However, even with that frugal capacity, if you have many small streams, having a small cluster for each one is still not practical.

For such situations, there are currently a few options:

  • Configure the stream DataFrame to feed from multiple Kafka topics or Kinesis streams. Then in the DataFrame, use the columns topic and streamName, for Kafka and Kinesis sources respectively, to determine how to handle the data (for example, different transformations or destinations). Make sure the DataFrame is cached, so you don’t read the data multiple times.
  • If you have a mix of Kafka and Kinesis sources, you can define a DataFrame for each, join them, and process as needed using the columns mentioned in the previous point.
  • The preceding two cases require all the sources to have the same batch interval and links their processing (for example, a busier stream can delay a slower one). To have independent stream processing inside the same cluster, you can trigger the processing of separate stream’s DataFrames using separate threads. Each stream is monitored separately in the Spark UI, but you’re responsible for starting and managing those threads and handle errors.

Settings

In this post, we showed some config settings that impact performance. The following table summarizes the ones we discussed and other important config properties to use when creating the input stream DataFrame.

Property Applies to Remarks
maxOffsetsPerTrigger Kafka Limit of messages per batch. Divides the limit evenly among partitions.
kinesis.executor.maxFetchRecordsPerShard Kinesis Limit per each shard, therefore should be revised if the number of shards changes.
kinesis.executor.maxFetchTimeInMs Kinesis When increasing the batch size (either by increasing the batch interval or the previous property), the executor might need more time, allotted by this property.
startingOffsets Kafka Normally you want to read all the data available and therefore use earliest. However, if there is a big backlog, the system might take a long time to catch up and instead use latest to skip the history.
startingposition Kinesis Similar to startingOffsets, in this case the values to use are TRIM_HORIZON to backload and LATEST to start processing from now on.
includeHeaders Kafka Enable this flag if you need to merge and split multiple topics in the same job (see the previous section for details).
kinesis.executor.maxconnections Kinesis When writing to Kinesis, by default it uses a single connection. Increasing this might improve performance.
kinesis.client.avoidEmptyBatches Kinesis It’s best to set it to true to avoid wasting resources (for example, generating empty files) when there is no data (like the Kafka connector does). GlueContext.forEachBatch prevents empty batches by default.

Further optimizations

In general, it’s worth doing some compression on the messages to save on transfer time (at the expense of some CPU, depending on the compression type used).

If the producer compresses the messages individually, AWS Glue can detect it and decompress automatically in most cases, depending on the format and type. For more information, refer to Adding Streaming ETL Jobs in AWS Glue.

If using Kafka, you have the option to compress the topic. This way, the compression is more effective because it’s done in batches, end-to-end, and it’s transparent to the producer and consumer.

By default, the GlueContext.forEachBatch function caches the incoming data. This is helpful if the data needs to be sent to multiple sinks (for example, as Amazon S3 files and also to update a DynamoDB table) because otherwise the job would read the data multiple times from the source. But it can be detrimental to performance if the volume of data is big and there is only one output.

To disable this option, set persistDataFrame as false:

glueContext.forEachBatch(
    frame=myStreamDataFrame,
    batch_function=processBatch,
    options={
        "windowSize": "30 seconds",
        "checkpointLocation": myCheckpointPath,
        "persistDataFrame":  "false"
    }
)

In streaming jobs, it’s common to have to join streaming data with another DataFrame to do enrichment (for example, lookups). In that case, you want to avoid any shuffle if possible, because it splits stages and causes data to be moved between nodes.

When the DataFrame you’re joining to is relatively small to fit in memory, consider using a broadcast join. However, bear in mind it will be distributed to the nodes on every batch, so it might not be worth it if the batches are too small.

If you need to shuffle, consider enabling the Kryo serializer (if using custom serializable classes you need to register them first to use it).

As in any AWS Glue jobs, avoid using custom udf() if you can do the same with the provided API like Spark SQL. User-defined functions (UDFs) prevent the runtime engine from performing many optimizations (the UDF code is a black box for the engine) and in the case of Python, it forces the movement of data between processes.

Avoid generating too many small files (especially columnar like Parquet or ORC, which have overhead per file). To do so, it might be a good idea to coalesce the micro-batch DataFrame before writing the output. If you’re writing partitioned data to Amazon S3, repartition based on columns can significantly reduce the number of output files created.

Conclusion

In this post, you saw how to approach sizing and tuning an AWS Glue streaming job in different scenarios, including planning considerations, configuration, monitoring, tips, and pitfalls.

You can now use these techniques to monitor and improve your existing streaming jobs or use them when designing and building new ones.


About the author

Gonzalo Herreros is a Senior Big Data Architect on the AWS Glue team.
Open APIs – Public Infrastructure in the Digital Age

Post Syndicated from Bozho original https://techblog.bozho.net/open-apis-public-infrastructure-in-the-digital-age/

When “public infrastructure” is mentioned, typically people think of roads, bridges, rails, dams, power plants, city lights. These are all enablers, publicly funded/owned/managed (not necessarily all of these), which allow the larger public to do business and to cover basic needs. Public infrastructure is sometimes free, but not always (you pay electricity bills and toll fees; and of course someone will rightly point out that nothing is free, because we pay it through taxes, but that’s not the point).

In the digital age, we can think of some additional examples to “public infrastructure”. The most obvious one, which has a physical aspects, is fiber-optic cables. Sometimes they are publicly owned (especially in rural areas), and their goal is to provide internet access, which itself is an enabler for business and day-to-day household activities. More and more countries, municipalities and even smaller communities invest in owning fiber-optic cables in order to make sure there’s equal access to the internet. But cables are still physical infrastructure.

Something entirely digital, that is increasingly turning into public infrastructure, are open government APIs. They are not fully perceived as public infrastructure, and exist as such only in the heads of a handful of policymakers and IT experts, but in essence they are exactly that – government-owned infrastructure that enables businesses and other activities.

But let me elaborate. Open APIs let the larger public access data and/or modify data that is collected and/or centralized and/or monitored by government institutions (central or local). Some examples:

  • Electronic health infrastructure – the Bulgarian government is building a centralized health record as well as centralized e-prescriptions and e-hospitalization. It is all APIs, where private companies develop software for hospitals, general practitioners, pharmacies, labs. Other companies may develop apps for citizens to help them improve their health or match them with nutrition and sport advice. All of that is based on open APIs (following the FHIR standard) and allows for fair competition, while managing access to sensitive data, audit logs and most importantly – collection in a centralized store.
  • Toll system – we have a centralized road toll system, which offers APIs (unfortunately, via an overly complicated model of intermediaries) which supports multiple resellers to sell toll passes (time-based and distance-based). This allows telecoms (through apps), banks (through e-banking), supermarkets, fleet management companies and others to offer better UI and integrated services.
  • Tax systems – businesses will be happy to report their taxes through their ERP automatically, rather than manually exporting and uploading, or manually filling data in complex forms.
  • E-delivery of documents – Bulgaria has a centralized system for electronic delivery of documents to public institutions. That system has an API, which allows third parties to integrate and send documents as part of more complex services, on behalf of citizens and organizations.
  • Car registration – car registers are centralized, but opening up their APIs would allow car (re)sellers to handle all the paperwork on behalf of their customers, online, by a click of a button in their internal system. Car part owners can fetch data about registered cars per brand and model in order to make sure there are enough spare parts in stock (based on the typical lifecycle of car parts).

Core systems and central registers with open APIs are digital public infrastructure that would allow a more seamless, integrated state. There are a lot of details to be taken into account – access management and authentication (who has the right to read or write certain data), fees (if a system is heavily used, the owning institution might charge a fee), change management and upgrades, zero downtime, integrity, format, etc.

But the policy that I have always followed and advocated for is clear – mandatory open APIs for all government systems. Bureaucracy and paperwork may become nearly invisible, hidden behind APIs, if this principle is followed.

The post Open APIs – Public Infrastructure in the Digital Age appeared first on Bozho's tech blog.

Manage data transformations with dbt in Amazon Redshift

Post Syndicated from Randy Chng original https://aws.amazon.com/blogs/big-data/manage-data-transformations-with-dbt-in-amazon-redshift/

Amazon Redshift is a fully managed, petabyte-scale data warehouse service in the cloud. You can start with just a few hundred gigabytes of data and scale to a petabyte or more. Amazon Redshift enables you to use your data to acquire new insights for your business and customers while keeping costs low.

Together with price-performance, customers want to manage data transformations (SQL Select statements written by data engineers, data analysts, and data scientists) in Amazon Redshift with features including modular programming and data lineage documentation.

dbt (data build tool) is a framework that supports these features and more to manage data transformations in Amazon Redshift. There are two interfaces for dbt:

  • dbt CLI – Available as an open-source project
  • dbt Cloud – A hosted service with added features including an IDE, job scheduling, and more

In this post, we demonstrate some features in dbt that help you manage data transformations in Amazon Redshift. We also provide the dbt CLI and Amazon Redshift workshop to get started using these features.

Manage common logic

dbt enables you to write SQL in a modular fashion. This improves maintainability and productivity because common logic can be consolidated (maintain a single instance of logic) and referenced (build on existing logic instead of starting from scratch).

The following figure is an example showing how dbt consolidates common logic. In this example, two models rely on the same subquery. Instead of replicating the subquery, dbt allows you to create a model for the subquery and reference it later.

Manage common subquery in dbt

Figure 1: Manage common subquery in dbt

The concept of referencing isn’t limited to logic related to subqueries. You can also use referencing for logic related to fields.

The following is an example showing how dbt consolidates common logic related to fields. In this example, a model applies the same case statement on two fields. Instead of replicating the case statement for each field, dbt allows you to create a macro containing the case statement and reference it later.

Manage common case statement in dbt

Figure 2: Manage common case statement in dbt

How is a model in dbt subsequently created in Amazon Redshift? dbt provides you with the command dbt run, which materializes models as views or tables in your targeted Amazon Redshift cluster. You can try this out in the dbt CLI and Amazon Redshift workshop.

Manage common data mappings

Although you can use macros to manage data mappings (for example, mapping “1” to “One” and “2” to “Two”), an alternative is to maintain data mappings in files and manage the files in dbt.

The following is an example of how dbt manages common data mappings. In this example, a model applies one-to-one data mappings on a field. Instead of creating a macro for the one-to-one data mappings, dbt allows you to create a seed for the one-to-one data mappings in the form of a CSV file and then reference it later.

Manage common data mapping in dbt

Figure 3: Manage common data mapping in dbt

You can create or update a seed with a two-step process. After you create or update a CSV seed file, run the command dbt seed to create the CSV seed as a table in your targeted Amazon Redshift cluster before referencing it.

Manage data lineage documentation

After you have created models and seeds in dbt, and used dbt’s referencing capability, dbt provides you with a method to generate documentation on your data transformations.

You can run the command dbt docs generate followed by dbt docs serve to launch a locally hosted website containing documentation on your dbt project. When you choose a model on the locally hosted website, information about the model is displayed, including columns in the final view or table, dependencies to create the model, and the SQL that is compiled to create the view or table. The following screenshot shows an example of this documentation.

Documentation generated by dbt

Figure 4: Documentation generated by dbt

You can also visualize dependencies for improved navigation of documentations during impact analysis. In the following example graph, we can see that model rpt_tech_all_users is built referencing the model base_public_users, which in turn references the table users in the public schema.

Data lineage visualization generated by dbt

Figure 5: Data lineage visualization generated by dbt

Conclusion

This post covered how you can use dbt to manage data transformations in Amazon Redshift. As you explore dbt, you will come across other features like hooks, which you can use to manage administrative tasks, for example, continuous granting of privileges.

For a hands-on experience with dbt CLI and Amazon Redshift, we have a workshop with step-by-step instructions to help you create your first dbt project and explore the features mentioned in this post—models, macros, seeds, and hooks. Visit dbt CLI and Amazon Redshift to get started.

If you have any questions or suggestions, leave your feedback in the comments section. If you need any further assistance to optimize your Amazon Redshift implementation, contact your AWS account team or a trusted AWS partner.


About the authors

Randy Chng is an Analytics Acceleration Lab Solutions Architect at Amazon Web Services. He works with customers to accelerate their Amazon Redshift journey by delivering proof of concepts on key business problems.

Sean Beath is an Analytics Acceleration Lab Solutions Architect at Amazon Web Services. He delivers proof of concepts with customers on Amazon Redshift, helping customers drive analytics value on AWS.

GitHub Availability Report: July 2022

Post Syndicated from Jakub Oleksy original https://github.blog/2022-08-03-github-availability-report-july-2022/

In July, we experienced one incident that resulted in degraded performance for Codespaces. This report also sheds light into two incidents in June that impacted multiple GitHub.com services.

July 27 22:29 UTC (lasting 5 hours and 55 minutes)

Our alerting systems detected degraded availability for Codespaces in the US West and East regions during this time. Due to the recency of this incident, we are still investigating the contributing factors and will provide a more detailed update on cause and remediation in the August Availability Report, which will publish the first Wednesday of September.

Follow up to June 28 17:16 UTC (lasting 26 minutes)

During this incident, Codespaces was made unavailable due to issues introduced when migrating a DNS record to a new load balancer.

Codespaces runs a set of microservices in each region where Codespaces can be created. In order to route requests to the nearest region for each user, we have a global DNS record that uses a load balancer to resolve to the nearest regional backend. When performing an infrastructure migration, we needed to switch this record to point to a new load balancer. In order to do that, we deleted the existing global record in order to replace it with a record that pointed to the new balancer. Unfortunately, adding the new replacement record failed. Thus, any requests made to the global DNS record that pointed to Codespaces services were denied. Our alerting systems detected this almost immediately; however, our attempt to rollback the DNS update to switch to the old configuration also failed. We then disabled an endpoint in the old load balancer, upon which the rollback succeeded and all metrics recovered (after some time due to DNS caching and TTL).

As a follow-up, we are investigating safer mechanisms for testing the new load balancers and atomic DNS record updates, including setting up a mirrored testing DNS zone. We are also following up with our cloud provider to understand why the initial rollback failed and whether this is a bug.

Follow up to June 29 14:48 UTC (lasting 1 hour and 27 minutes)

During this incident, services including GitHub Actions, API Requests, Codespaces, Git Operations, GitHub Packages, and GitHub Pages were impacted. This was due to excessive load on a proxy server that routes traffic to the database.

At approximately 14:14 UTC, the internal APIs that a data migration service uses to communicate with GitHub.com began returning 502 Service Unavailable errors to requests. This migration service allows customers to migrate to GitHub.com from other external sources, including GitHub Enterprise Server. As part of its exception handling, the service contains retry logic to requeue jobs. However, this logic captured all exceptions rather than just a subset. The 502 errors it caught triggered a bug that caused jobs to continuously requeue themselves to be retried. The situation quickly escalated when hundreds of thousands of jobs made identical API requests, overwhelming the database’s proxy server.

We mitigated the situation by pausing the processing of all new customer-initiated migrations performed with the data migration service at 15:07 UTC. We also pruned the queues of all jobs associated with in-progress migrations to alleviate the pressure on the proxy server. Approximately nine minutes later, we began to see affected services recover.

We have updated exception handling to only retry jobs in cases of a specific set of errors. We have also adjusted our logic to retry a fixed number of times before logging the exception and giving up. These actions eliminate the possibility of continuous requeuing. We are also investigating whether changes are needed to the rate limits of our internal APIs.

In summary

Please follow our status page for real-time updates on status changes. To learn more about what we’re working on, check out the GitHub Engineering Blog.

OCCRP: Власти Болгарии пытались тайно поставить в Украину дефектные боеприпасы на $200 млн.

Post Syndicated from Николай Марченко original https://bivol.bg/occrp-%D0%B2%D0%BB%D0%B0%D1%81%D1%82%D0%B8-%D0%B1%D0%BE%D0%BB%D0%B3%D0%B0%D1%80%D0%B8%D0%B8-%D0%BF%D1%8B%D1%82%D0%B0%D0%BB%D0%B8%D1%81%D1%8C-%D1%82%D0%B0%D0%B9%D0%BD%D0%BE-%D0%BF%D0%BE%D1%81%D1%82.html

сряда 3 август 2022


Расследование сайта “Биволъ” опубликовано с сокращениями в русскоязычной версии сайта Organized Crime and Corruption Reporting Project (OCCRP). Перепечатано с разрешения OCCRP.  Журналисты партнерских центров OCCRP «Биволъ» (Болгария) и Fundacja Reporterów…

Vetter: Locking engineering hierarchy

Post Syndicated from original https://lwn.net/Articles/903681/

Daniel Vetter continues his
series
on locking in the kernel.

This part goes through a pile of locking pattern and designs, from
most favourable and easiest to adjust and hence resulting in a long
term maintainable code base, to the least favourable since hardest
to ensure it works correctly and stays that way while the code
evolves. For convenience even color coded, with the dangerous
levels getting progressively more crispy red indicating how close
to the burning fire you are! Think of it as Dante’s Inferno, but
for locking.

The Future of the SOC Is XDR

Post Syndicated from Dina Durutlic original https://blog.rapid7.com/2022/08/03/the-future-of-the-soc-is-xdr/

The Future of the SOC Is XDR

Extended detection and response (XDR) is increasingly gaining traction across the industry. In a new research ebook sponsored by Rapid7, SOC Modernization and the Role of XDR, ESG identified that 61% of security professionals claim that they are very familiar with XDR technology. While this is an improvement from ESG’s 2020 research (when only 24% of security professionals were very familiar with XDR), 39% are still only somewhat familiar, not very familiar, or not at all familiar with XDR.

Security professionals are still unsure of all the associated capabilities that they can leverage with XDR, and frankly how to define the solution. ESG reports that 55% of respondents say that XDR is an extension of endpoint detection and response (EDR), while 44% believe XDR is a detection and response product from a single security technology vendor or an integrated and heterogeneous security product architecture designed to interoperate and coordinate on threat prevention, detection, and response. Nevertheless, XDR remains to be standardized in the industry.

Keeping up with threats

XDR, as defined by Rapid7, goes beyond simple data aggregation. It unifies and transforms relevant security data across a modern environment to detect real attacks. XDR provides security teams with high context and actionable insights to extinguish threats quickly. With XDR, organizations can operate efficiently, reduce noise, and help zero in on attacks early.

According to ESG, security professionals seem to have a number of common XDR use cases in mind. 26% of security professionals want XDR to help prioritize alerts based on risk, 26% seek improved detection of advanced threats, 25% want more efficient threat/forensic investigations, 25% desire a layered addition to existing threat detection tools, and 25% think XDR could improve threat detection to reinforce security controls and prevent future similar attacks.

The theme and core capabilities that are common align with filling in gaps within the security tech stack – while improving threat detection and response.

Holistic detection and response

More than half of security professionals, surveyed by ESG, believe XDR will supplement existing security operations technologies; 44% of those surveyed see XDR as consolidating current security operations technologies into a common platform.

Security operation center (SOC) analysts struggle with numerous disparate tools and systems. It often leads to having to sift through a lot of data (often noise) and context-switching (moving from one tool to another). XDR aims to:

  • Unify broad telemetry sources (e.g. users, endpoints, cloud, network, etc.) into a single view and set of detections. It helps analysts curate detections, comprehensive investigations, and much more ultimately enabling simpler, smarter, and faster executions.
  • Embed expertise to help guide incident response (e.g. recommendation actions and next steps, automations, etc.) to enable security professionals to respond to threats with a single click – or without resource involvement.
  • Empower security teams to be more proactive around detection and response by enabling hunting, guiding forensic and investigation use cases, and more automation to streamline SecOps.
  • Unlock greater efficiency and efficacy for security teams at each step of the detection and response journey (from initial deployment and data collection, to finding threats and incident response).

Regardless of how XDR is defined, security professionals are interested in using XDR to help them address several threat detection and response challenges. InsightIDR, Rapid7’s cloud-native SIEM and XDR, is an XDR solution before it was even “coined” and users are achieving XDR outcomes. XDR has improved security efficacy and efficiency, unified data, and helped streamline security operations.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

How to track AWS account metadata within your AWS Organizations

Post Syndicated from Jonathan Nguyen original https://aws.amazon.com/blogs/architecture/how-to-track-aws-account-metadata-within-your-aws-organizations/

United States Automobile Association (USAA) is a San Antonio-based insurance, financial services, banking, and FinTech company supporting millions of military members and their families. USAA has partnered with Amazon Web Services (AWS) to digitally transform and build multiple USAA solutions that help keep members safe and save members’ money and time.

Why build an AWS account metadata solution?

The USAA Cloud Program developed a centralized solution for collecting all AWS account metadata to facilitate core enterprise functions, such as financial management, remediation of vulnerable and insecure configurations, and change release processes for critical application and infrastructure changes.

Companies without centralized metadata solutions may have distributed documents and wikis that contain account metadata, which has to be updated manually. Manually inputting/updating information generally leads to outdated or incorrect metadata and, in addition, requires individuals to reach out to multiple resources and teams to collect specific information.

Solution overview

USAA utilizes AWS Organizations and a series of GitLab projects to create, manage, and baseline all AWS accounts and infrastructure within the organization, including identity and access management, security, and networking components. Within their GitLab projects, each deployment uses a GitLab baseline version that determines what version of the project was provisioned within the AWS account.

During the creation and onboarding of new AWS accounts, which are created for each application team and use-case, there is specific data that is used for tracking and governance purposes, and applied across the enterprise. USAA’s Public Cloud Security team took an opportunity within a hackathon event to develop the solution depicted in Figure 1.

  1. AWS account is created conforming to a naming convention and added to AWS Organizations.

Metadata tracked per AWS account includes:

    • AWS account name
    • Points of contact
    • Line of business (LOB)
    • Cost center #
    • Application ID #
    • Status
    • Cloud governance record #
    • GitLab baseline version
  1. Amazon EventBridge rule invokes AWS Step Functions when new AWS accounts are created.
  2. Step Functions invoke an AWS Lambda function to pull AWS account metadata and load into a centralized Amazon DynamoDB table with Streams enabled to support automation.
  3. A private Amazon API Gateway is exposed to USAA’s internal network, which queries the DynamoDB table and provides AWS account metadata.
Overview of USAA architecture automation workflow to manage AWS account metadata

Figure 1. Overview of USAA architecture automation workflow to manage AWS account metadata

After the solution was deployed, USAA teams leveraged the data in multiple ways:

  1. User interface: a front-end user-interface querying the API Gateway to allow internal users on the USAA network to filter and view metadata for any AWS accounts within AWS Organizations.
  2. Event-driven automation: DynamoDB streams for any changes in the table that would invoke a Lambda function, which would check the most recent version from GitLab and the GitLab baseline version in the AWS account. For any outdated deployments, the Lambda function invokes the CI/CD pipeline for that AWS account to deploy a standardized set of IAM, infrastructure, and security resources and configurations.
  3. Incident response: the Cyber Threat Response team reduces mean-time-to-respond by developing automation to query the API Gateway to append points-of-contact, environment, and AWS account name for custom detections as well as Security Hub and Amazon GuardDuty findings.
  4. Financial management: Internal teams have integrated workflows to their applications to query the API Gateway to return cost center, LOB, and application ID to assist with financial reporting and tracking purposes. This replaces manually reviewing the AWS account metadata from an internal and manually updated wiki page.
  5. Compliance and vulnerability management: automated notification systems were developed to send consolidated reports to points-of-contact listed in the AWS account from the API Gateway to remediate non-compliant resources and configurations.

Conclusion

In this post, we reviewed how USAA enabled core enterprise functions and teams to collect, store, and distribute AWS account metadata by developing a secure and highly scalable serverless application natively in AWS. The solution has been leveraged for multiple use-cases, including internal application teams in USAA’s production AWS environment.

Building and using Managed Components with WebCM

Post Syndicated from Yo'av Moshe original https://blog.cloudflare.com/building-using-managed-components-webcm/

Building and using Managed Components with WebCM

Building and using Managed Components with WebCM

Managed Components are here to shake up the way third-party tools integrate with websites. Two months ago we announced that we’re open sourcing parts of the most innovative technologies behind Cloudflare Zaraz, making them accessible and usable to everyone online. Since then, we’ve been working hard to make sure that the code is well documented and all pieces are fun and easy to use. In this article, I want to show you how Managed Components can be useful for you right now, if you manage a website or if you’re building third-party tools. But before we dive in, let’s talk about the past.

Third-party scripts are a threat to your website

For decades, if you wanted to add an analytics tool to your site, a chat widget, a conversion pixel or any other kind of tool – you needed to include an external script. That usually meant adding some code like this to your website:

<script src=”https://example.com/script.js”></script>

If you think about it – it’s a pretty terrible idea. Not only that you’re now asking the browser to connect to another server, fetch and execute more JavaScript code – you’re also completely giving up the control on your website. How much do you really trust this script? And how much do you trust that the script’s server wasn’t hacked, or will never get hacked in the future? In the previous blog post we showed how including one script usually results in more network calls, hogging the browser and slowing everything down. But the worst thing about these scripts is that they are completely unrestricted: JavaScript code running in the browser can hijack users, steal their credentials or credit card information, use their devices to mine cryptocurrencies, manipulate your website, leak PII, and more. Since the code in those scripts is usually minified, it’s practically impossible for you to read it and figure out what it’s doing.

Managed Components change all that. Like apps on your phone, they’re built around a permissions system. You decide if you allow a component to connect to a remote server, if you allow it to use cookies, to run code, to inject a widget to pages and more. Unlike the world of minified external scripts, it is a framework that promotes transparency. Website owners can toggle permissions on and off, and if a Managed Component wasn’t granted a permission, it will not have access to the relevant API.

But Managed Components do more than wrapping the current system with permissions – they also provide functionality that was never available before: making server-side connections, caching information, using a key-value store, manipulating responses before they are handed to the browser and more. The core of this functionality comes from the ability to execute code outside the browser. Freeing the browser from running code that was previously executed in the browser, means that your website can become approximately 40% faster. It also results in a smaller attack surface in case your tool’s vendor gets hacked.

All of this is possible thanks to the new Managed Components API. We designed it together with vendors, to make sure you can use them to write any tool, while keeping performance, security and privacy a top priority. At its core, a Managed Component is just a JavaScript module, and so every JavaScript developer should feel right at home when building one. Check out the two examples in our previous blog post to see how they actually look like, or see some Managed Components we already open sourced on GitHub.

WebCM is the open source Component Manager

When tools are loaded with a <script> tag, their code is executed by the browser. Since Managed Components don’t run in the browser, their code needs to be executed somewhere else. This is the Component Manager. We designed the APIs around Managed Components deliberately to not be tied to a specific Component Manager, and in fact, there are already two in the world: Cloudflare Zaraz, and WebCM.

WebCM, Web-based Component Manager, is our open source reference implementation of a Component Manager. If you run a website, you can use WebCM today to run Managed Components on your website, even if you’re not a Cloudflare user. If you want to create a Managed Component, you can use it like an SDK.

Over the last few months, we’ve been helping vendors to write their own Managed Components, and we will continue to do so. We open sourced WebCM to ensure that Managed Components are a technology of the Web as a whole. Everyone should be able to use WebCM to load and create Managed Components. Let’s see how to use it!

Getting started with WebCM in 5 minutes

Getting started with WebCM is easier than you think. Because WebCM works like a proxy, you can use it regardless of how your website is built. In a new folder, create a simple HTML file and call it index.html:

<!DOCTYPE html>
<html lang=”en”>
  <head>
	<meta charset="UTF-8">
	<title>My Website</title>
  </head>
  <body>
    	<h1>WebCM test website</h1>  
  </body>
</html>

Let’s serve this file by launching an HTTP serve in the same folder:

You can use Node.js:

npx http-server -p 8000

You can use Python:

python3 -m http.server

Or anything else that would serve our HTML file on http://localhost:8000/index.html.

Next, create a configuration file for WebCM. In a new directory, create a file called webcm.config.ts.

export default {
  components: [
    {
      name: 'demo',
      permissions: [
        'access_client_kv',
        'provide_server_functionality',
        'provide_widget',
        'serve_static_files',
        'client_network_requests',
      ],
    },
  ],
  target: 'http://127.0.0.1:8000',
  hostname: 'localhost',
  trackPath: '/webcm/track',
  ecommerceEventsPath: '/webcm/ecommerce',
  clientEventsPath: '/webcm/system',
  port: 8080
}

Let’s go over this configuration file:

  • components is an array that lists all the Managed Components you want to load. For now, we will load the demo component. Note that all we needed was to specify “demo”, and WebCM will go and get it from NPM for us. Other Managed Components are available on NPM too, and you can install components from other sources too. For each component, we’re defining what permissions we are giving it. You can read more about the permissions in the specifications. If we try to add the component without granting it its required permissions, WebCM will alert us.
  • target is where our origin HTTP server runs. In the previous step, we set it to run on port 8000.
  • port is the port under which WebCM will serve our website.
  • hostname is the host WebCM will bind to.
  • trackPath, clientEventsPath, ecommerceEventsPath are paths that WebCM will use to send events from the browser to its backend. We can leave these paths as they are for now, and will see how they’re used later.

! Note: Node version 17 or higher is needed for the next section

While keeping your HTTP server running, and in the same directory as webcm.config.ts, run npx webcm. Node will fetch WebCM and start it for you, and WebCM will read the configuration. First, it will fetch the required components to a components folder. When done, it will start another server that proxies your origin.

If you open http://localhost:8080/index.html in your browser now, you’d see the same page you saw at http://localhost:8000/index.html. While the pages might look similar, the one running on port 8080 has our demo Managed Component running. Moving your mouse and clicking around the page should result in messages being printed in your WebCM terminal, showing that the component was loaded and that it is receiving data. You will also notice that the page now displays a simple weather widget – this a Managed Component Widget that got appended to your page. The weather information was fetched without the browser needing to contact any additional server, and WebCM can cache that information to make sure it is served fast. Lastly, if you go to http://localhost:8080/webcm/demo/cheese, you’ll see that the component is serving a static image of a cheese. This is an example of how Managed Components can expose new endpoints on your servers, if you allow them.

The Demo Component, like its name suggests, is just a demo. We use it to showcase and test the Managed Components APIs. What if we want to add a real Managed Component to our site? Google Analytics is used by more than half of the websites on the internet, so let’s see how we edit our webcm.config.ts file to load it.

export default {
  components: [
    {
      name: 'demo',
      permissions: [
        'access_client_kv',
        'provide_server_functionality',
        'provide_widget',
        'serve_static_files',
        'client_network_requests',
      ],
    },
    {
      name: 'google-analytics',
      settings: { 'tid': 'UA-XXXXXX' },
      permissions: [
        'access_client_kv',
      ],
    },
  ],
  target: 'http://127.0.0.1:8000',
  hostname: 'localhost',
  trackPath: '/webcm/track',
  ecommerceEventsPath: '/webcm/ecommerce',
  clientEventsPath: '/webcm/system',
  port: 8080
}

In the above example, we just replaced our demo component with the Google Analytics Managed Component. Note that this component requires much fewer permissions to run – that’s because it is running 100% server-side. Remember to replace UA-XXXXXX with your real Google Universal Analytics (version 3) account identifier.

Re-running `npx webcm` will now fetch the google-analytics Managed Component and run it, with the settings you provided. If you go now to your proxied website, you won’t see anything changed. But if you go to your Google Analytics dashboard, you will start seeing page views appearing on the Real Time view. WebCM loaded the component and is sending information server-side to Google Analytics.

There are many other components you can play around with, and we’re adding more all the time. Check out the Managed Components organization on NPM or on GitHub to see the full list.

Build your own Managed Component

Managed Components isn’t a closed library of tools you can use. As mentioned before – we are gradually open sourcing more tools from our library on GitHub. If you think our components are doing something weird – please let us know with an issue, or even make a PR. Managed Components are for the benefit of everyone. Over the past few months, the Cloudflare Zaraz community on Discord and on the Cloudflare Community Forum was extremely helpful in actively reporting issues, and so we’re excited to give them the option to take one step closer to the internals behind Cloudflare Zaraz.

While improving existing Managed Components is great, the thing we’re most thrilled about is that you can now build your own Managed Components too. If you’re a third-party tool vendor – this is a way for you to create a version of your tool that is safe and performant, so customers can discover and adopt your tool easily. If you’re a website developer, you might want to tinker with Managed Components to see what kind of things you can easily move away from the browser, for performance gains.

Let’s see how easy it is to create a Managed Component that listens to every page view on our website. Run npm init managed-component in the components directory that WebCM created, and create-managed-component will take you through the process of scaffolding your component files. To start with, our component will not use any special permissions, so you can select none.

Once we’re done with the wizard, we can open our src/index.ts file. By default, our component will add a listener to all page views:

import { ComponentSettings, Manager } from '@managed-components/types'

export default async function (manager: Manager, settings: ComponentSettings) {
  manager.addEventListener('pageview', event => {
    // do the things
  })
}

Let’s edit the comment line so that we can see whenever a page view happens. Note we also prefixed settings with a _ because we’re not using it now:

import { ComponentSettings, Manager } from '@managed-components/types'

export default async function (manager: Manager, _settings: ComponentSettings) {
  manager.addEventListener('pageview', event => {
    console.log(`New pageview at ${event.client.url}`)
  })
}

With these changes, the component will print the current URL whenever a page is viewed on the website. Before trying it out, we need to build our component. In the folder of your component run npm i && npm run build. Then, use the namespace of your component to add it to your webcm.config.ts file and restart WebCM:

export default {
  components: [
    {
      name: 'demo',
      permissions: [
        'access_client_kv',
        'provide_server_functionality',
        'provide_widget',
        'serve_static_files',
        'client_network_requests',
      ],
    },
    {
      name: 'google-analytics',
      settings: { 'tid': 'UA-123456' },
      permissions: [
        'access_client_kv',
      ],
    },
    {
      name: 'your-component-namespace',
      settings: {},
      permissions: [],
    },
  ],
  target: 'http://127.0.0.1:8000',
  hostname: 'localhost',
  trackPath: '/webcm/track',
  ecommerceEventsPath: '/webcm/ecommerce',
  clientEventsPath: '/webcm/system',
  port: 8080
}

This is a very simple component, but it shows how easy it is to build functionality that was previously only available in the browser. You can easily extend your component: use fetch next to the console.log statement and send information to your own analytics warehouse whenever a pageview happens on your site. Read about all the other Managed Components APIs to create widgets, listen to clicks, store cookies, use cache, and much more. These APIs allow you to build richer tools than it was ever possible before.

Your tool is better as a Managed Component

When we started working on Managed Components, many people were asking what would be the motivation of a tool vendor to build a Managed Component. During these last few months, we’ve learned that vendors are often excited about Managed Components for the same reasons we are – it provides a safe way to use their tools, and a streamlined way to integrate their tools in websites. Customers care deeply for these things, so having a Managed Component means that customers are more likely to try out your technology. Vendors will also get huge discoverability benefits, as their tools could be featured in the Cloudflare Zaraz dashboard, exposing them to tens of thousands of Zaraz-enabled websites. We are getting a lot of interest from major vendors in building a Managed Component, and we’re doing our best in actively supporting them in the process. If your company is interested in having a Managed Component, contact us.

We strongly believe that Managed Components can change the way third-party tools are used online. This is only the beginning of making them faster, secure and private. Together with users, and vendors, we will work on constantly improving the capabilities of Managed Components as a community, for the benefit of every user of the World Wide Web. To get started with building your Managed Component, head to managedcomponents.dev and start building. Our team is available to help you at [email protected].

The collective thoughts of the interwebz