Bookblaze 2025: Backblaze Employee Recommended Reads

Post Syndicated from Stephanie Doyle original https://www.backblaze.com/blog/bookblaze-2025-backblaze-employee-recommended-reads/
A decorative image showing several books on a holiday background.

Sure, we may be a global tech company who spends our days on the front lines of helping our customers solve their toughest data storage challenges, but that doesn’t mean we don’t ever power down the devices and curl up with a good book. Welcome to the third annual Bookblaze, Backblaze’s much-anticipated book guide where our team shares the stories, insights, and adventures that shaped their reading year. 

From thought-provoking nonfiction to immersive fiction and unexpected gems, these recommendations are curated by the people who read, think, and create here at Backblaze—offering you a cozy companion for winter nights, inspiration for your 2026 reading list, and maybe even the perfect gift idea along the way. Whether you’re reconnecting with old favorites or discovering your next great read, we hope this year’s picks spark joy, curiosity, and conversation.

Chris McGranahan, Director, Information Security Architecture
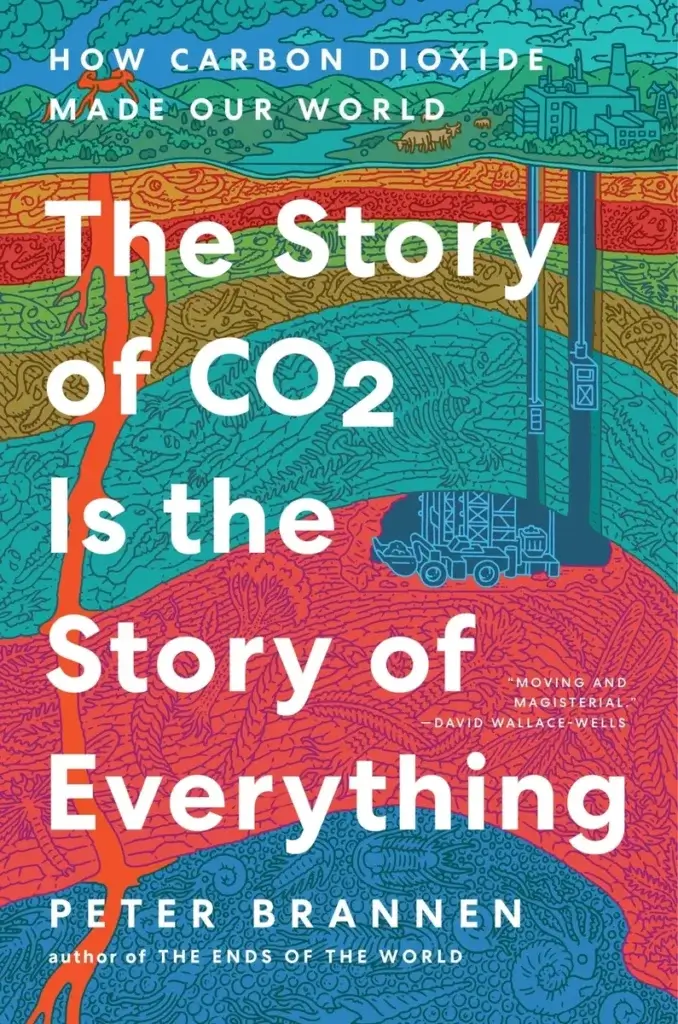
An image of the cover of The Story of CO2 Is the Story of Everything by Peter Brannen.

The Story of CO2 Is the Story of Everything, by Peter Brannen

It’s an exhaustive but entertaining explanation of how our world came to be the way it is, why CO2 is so important to it and how the path we’re currently on is likely to create a world that hasn’t existed in millions of years and never supported humans. And, if you want a fun fiction read, check out any of the Murderbot Diaries series by Martha Wells.

Maddie Presland, Product Marketing Manager
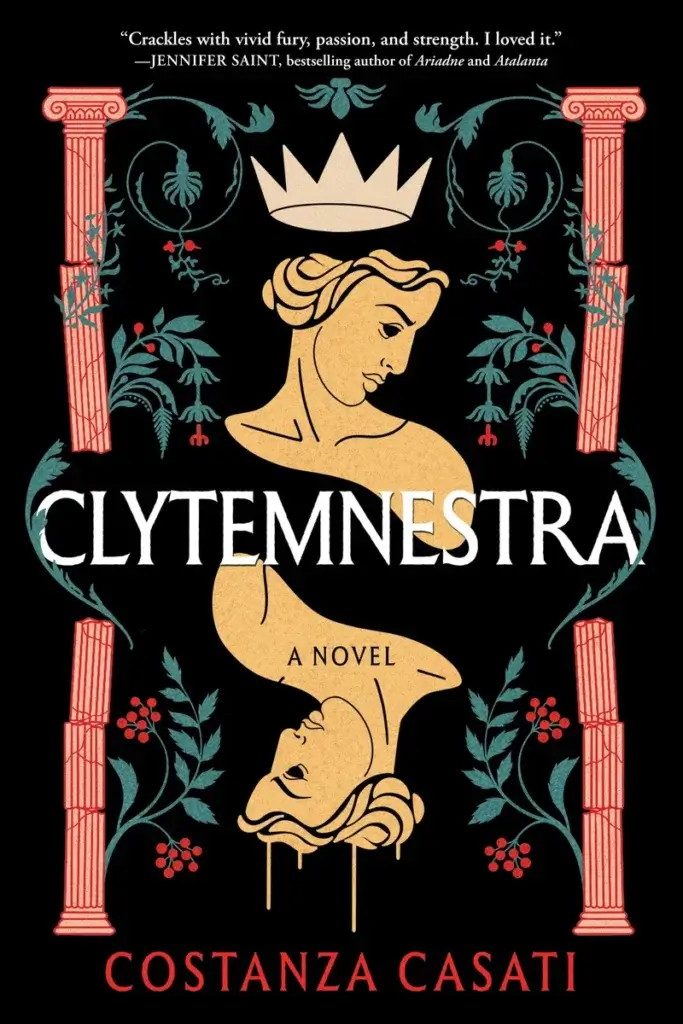
An image of the cover of the book Clytemnestra, by Costanza Casati.

Clytemnestra, by Costanza Casati

I love deeply flawed female protagonists. I also love the fact that myth retellings have been so popular for the last few years, and this year, I decided to tackle my hyper-specific TBR I was neglecting. (Editor’s note: For those of you not afflicted with chronic book collecting, TBR = to be read.) 

Clytemnestra tells the story of one of the most reviled women in Greek mythology. She’s cunning, ruthless, and quite possibly the original champion of playing the long game to seek revenge, as a key player in the Trojan War you’ve probably never heard of. And yet, you can’t help but root for her. It’s shocking that this is a debut novel because, though it can be a slow burn in parts, the characterization and completely immersive writing provides a different perspective of how the Trojan War unfolded for those left at home.

Bala Krishna Gangisetty, Sr. Product Manager
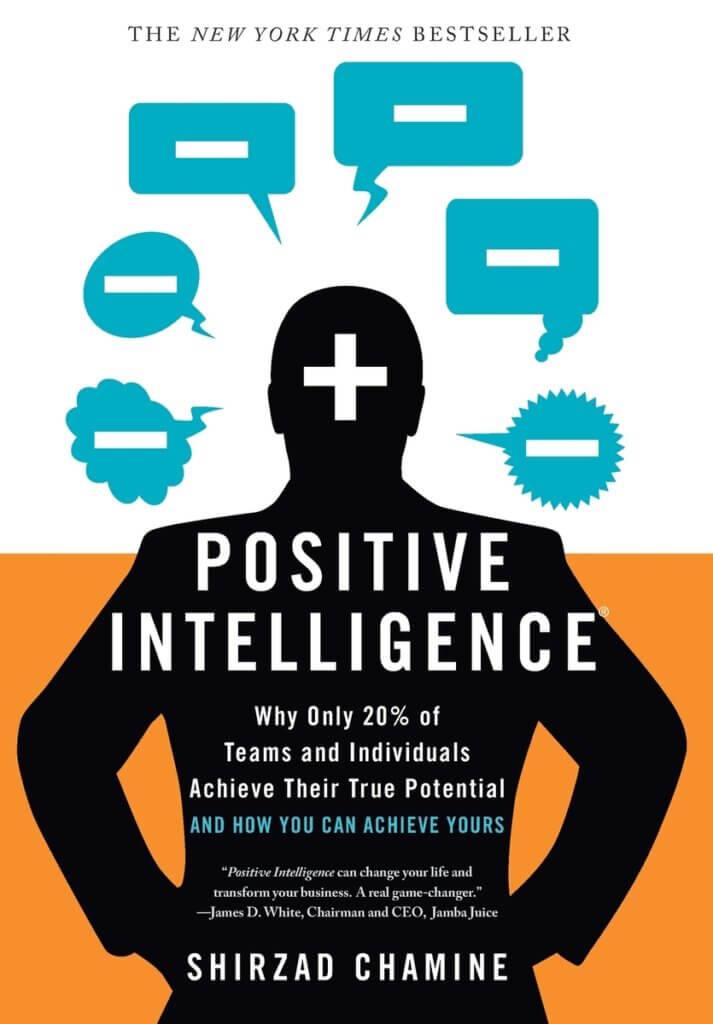
An image of the cover of the book Positive Intelligence, by Shirzad Chamine.

Positive Intelligence, by Shirzad Chamine

I appreciate how Positive Intelligence translates mindset and emotional intelligence into practical exercises for building mental fitness. The Saboteur framework makes it easy to spot negative thinking and shift toward a more productive mindset. It’s a great balance of psychology, neuroscience, and real-world application that supports personal and professional growth.

AJ Sedlak, Director, GTM and Marketing Operations
An image of the cover the book Essentialism: The Disciplined Pursuit of Less, by Greg McKeown.

Essentialism: The Disciplined Pursuit of Less, by Greg McKeown

In work and in life, we often struggle with saying “no”, even to ourselves. We take on more than we can effectively manage and execute. As a result, we’re burned out—frustrated by our ever-growing to-do lists and disappointed in the quality of what we do get done. This book helped me understand why doing less actually results in accomplishing more and better things. In addition, it gave me a sense of how to make this case to others—whether it’s about prioritization of work projects or helping a loved one who’s feeling overwhelmed.

Amy Kunde, Sr. Executive Assistant
An image of the cover of the book The Extraordinary Life of Sam Hell, by Robert Dugoni.

The Extraordinary Life of Sam Hell, by Robert Dugoni

Although there were some dark moments in the book, in general it was a feel good book of a boy coming of age through adulthood, paying his dues and then paying it forward.  The setting is right in the Backblaze neighborhood so it’s always interesting to picture the local intersections, and schools referenced in the novel.

Elisa Miller, Sr. Organizational Development Partner
An image of the cover of the book Parable of the Sower, by Octavia Butler.

Parable of the Sower, by Octavia Butler

Octavia Butler is a masterful sci fi writer who has woven a tale in the 1990s set to present time about a dystopian reality oddly similar to the one we are living/heading towards currently of lawlessness, greed, and the quest for survival. Focusing on the power of community, togetherness, and nature, this book was an epic (and scary) adventure into what happens when people gather together to fight the status quo while lifting one another up. It’s not for the faint of heart, but it really was a game changer for me to read, offering solutions beyond capitalism and towards empowerment of humanity, spirituality, and purpose. 

Molly Clancy, Sr. Manager, Content & Creative
An image of the cover of the book Project Hail Mary, by Andy Weir.

Project Hail Mary, by Andy Weir

It’s a buddy comedy, but also the fate of the human race is at stake. There’s lots of science to nerd out on if that’s your thing. And Andy Weir is a former software engineer, so you could kinda sorta say it’s “for work.”

Beth Grey, Sr. Risk & Regulatory Compliance Specialist
An image of the cover of the book The Happy Sleeper: The Science-Backed Guide to Helping Your Baby Get a Good Night's Sleep-Newborn to School Age, by Heather Turgeon, MFT, and Julie Wright, MFT.

The Happy Sleeper: The Science-Backed Guide to Helping Your Baby Get a Good Night’s Sleep-Newborn to School Age, by Heather Turgeon, MFT, and Julie Wright, MFT

Sleep training my child without having to resort to too much crying seemed daunting, but this book helped inform our process with evidence based guidance. I am happy to report that I have a great little sleeper because of it. This book will help any parent gain the skills and confidence to effectively sleep train their child.

Yev Pusin, Head of Communications and Community
An image of the cover of the book Dungeon Crawler Carl, by Matt Dinniman.

Dungeon Crawler Carl, by Matt Dinniman

This book series is absolute insanity, and if you are able to get the audiobook, you will not regret it. I even got my sister’s mother-in-law to listen to it on audio and she loved it. The premise is that it’s the end of the world, and Carl is sucked into a dungeon to fight for the entertainment of the universe at large—plus there’s a talking cat! What’s not to like? It’s a genre known as LitRPG (editor’s note: Literary role-playing game) which follows Carl and his friends’ progression as they work through the dungeon and try to topple the powers that be.

Nicole Gale, Sr. Marketing Operations Manager
An image of the cover of the book The Ballad of Songbirds and Snakes, by Suzanne Collins.

The Ballad of Songbirds and Snakes, by Suzanne Collins

The new “Hunger Games” book is the first prequel I’ve read in years that genuinely adds something meaningful to its original series. It pulled me right back into Panem, had me rewatching all the movies, and had me loving characters that I didn’t expect to get attached to. A fantastic return to a world I thought I already knew.

Stephanie Doyle, Writer and Content Operations Strategist
An image of the cover of the book Children of Time, by Adrian Tchaikovsky.

Children of Time, by Adrian Tchaikovsky

This series reminds me of old-school science fiction in all the best ways. Without giving too much away, a terraforming project is sabotaged, leading to unexpected outcomes for the targeted planet. Meanwhile, back on Earth, the world ends, and a race begins for the remainder of humanity to find a new home. Tchaikovsky’s brilliance thrives in the details of understanding systems, people, biology, engineering, and science, and each new revelation about what’s happening—in this new world with a new sentient species, and with the humans on their ever-devolving arc ship—stems from each of those details showing up in ways that feel both expected and unexpected at the same time.

The post Bookblaze 2025: Backblaze Employee Recommended Reads appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Someone Boarded a Plane at Heathrow Without a Ticket or Passport

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/12/someone-boarded-a-plane-at-heathrow-without-a-ticket-or-passport.html

I’m sure there’s a story here:

Sources say the man had tailgated his way through to security screening and passed security, meaning he was not detected carrying any banned items.

The man deceived the BA check-in agent by posing as a family member who had their passports and boarding passes inspected in the usual way.

A change of maintainership for linux-next

Post Syndicated from corbet original https://lwn.net/Articles/1051179/

Stephen Rothwell, who has maintained the kernel’s linux-next integration
tree from its inception, has announced his
retirement from that role:

I will be stepping down as Linux-Next maintainer on Jan 16, 2026.
Mark Brown has generously volunteered to take up the challenge. He
has helped in the past filling in when I have been unavailable, so
hopefully knows what he is getting in to. I hope you will all
treat him with the same (or better) level of respect that I have
received.

It has been a long but mostly interesting task and I hope it has
been helpful to others. It seems a long time since I read Andrew
Morton’s “I have a dream” email and decided that I could help out
there – little did I know what I was heading for.

Over the last two decades or so, the kernel’s development process has evolved
from an unorganized mess with irregular releases to a smooth machine with a
new release every nine or ten weeks. That would not have happened without
linux-next; thanks are due to Stephen for helping to make the current
process possible.

[$] Episode 29 of the Dirk and Linus show

Post Syndicated from corbet original https://lwn.net/Articles/1050317/

Linus Torvalds is famously averse to presenting prepared talks, but the
wider community is always interested in what he has to say about the
condition of the Linux kernel. So, for some time now, his appearances have
been in the form of an informal conversation with Dirk Hohndel. At the
2025 Open Source Summit Japan, the pair followed that tradition for the
29th time. Topics covered include the state of the development process,
what Torvalds actually does, and how machine-learning tools might fit into
the kernel project.

How Kaltura Accelerates CI/CD Using AWS CodeBuild-hosted Runners

Post Syndicated from Michael Shapira original https://aws.amazon.com/blogs/devops/how-kaltura-accelerates-ci-cd-using-aws-codebuild-hosted-runners/

Kaltura, a leading AI video expirience cloud and corporate communications technology provider, transformed CI/CD infrastructure by migrating to AWS CodeBuild-hosted runners for GitHub Actions. This migration reduced DevOps operational overhead by 90%, accelerated build queue times by 66%, and cut infrastructure costs by 60%. Most importantly, the migration achieved these results while supporting Kaltura’s scale: over 1,000 repositories, 100+ distinct workflow types, and 1,300 daily builds across multiple development teams.

As organizations scale their engineering operations, maintaining efficient CI/CD infrastructure becomes increasingly critical. While tools like GitHub Actions simplify pipeline creation, managing the underlying infrastructure can become a significant burden for engineering teams, particularly when dealing with security requirements and private network access needs. For Kaltura, this challenge became acute as the company rapidly grew its engineering teams and onboarded new microservices weekly.

In this post, you’ll see how Kaltura modernized CI/CD infrastructure by migrating from self-managed Amazon Elastic Kubernetes Service (Amazon EKS) runners to CodeBuild-hosted runners, implementing enhanced security features while dramatically improving performance and reducing operational overhead.

Overview of Challenge and Solution

Understanding Self-Hosted Runners

GitHub-hosted runners offer zero operational overhead, automatic scaling, and a clean slate for each job, making them an excellent choice for many development teams. However, for enterprises like Kaltura with specific security and operational requirements, self-hosted runners provided a better fit. GitHub-hosted runners operate in a shared environment that, while secure, doesn’t offer the same level of granular control that enterprises may need for sensitive workloads. By moving to self-hosted runners on AWS, Kaltura gained access to robust security controls like Amazon Virtual Private Cloud (Amazon VPC) isolation, AWS Identity and Access Management (IAM) policies, and fine-grained access management. Additionally, self-hosted runners allowed Kaltura to customize hardware configurations for their specialized needs, optimize costs for their specific usage patterns, and maintain direct access to private network resources essential for their operations.

Self-hosted runners, which were initially implemented, offered the control Kaltura needed. By deploying runners within Amazon VPC, Kaltura gained crucial capabilities for enterprise-scale operations. The implementation enabled direct access to internal resources while implementing granular permissions through IAM roles. Using Amazon endpoints allowed Kaltura to avoid public API requests, ensuring all traffic remained within the organization’s secure private network.

The initial solution based on Amazon EKS

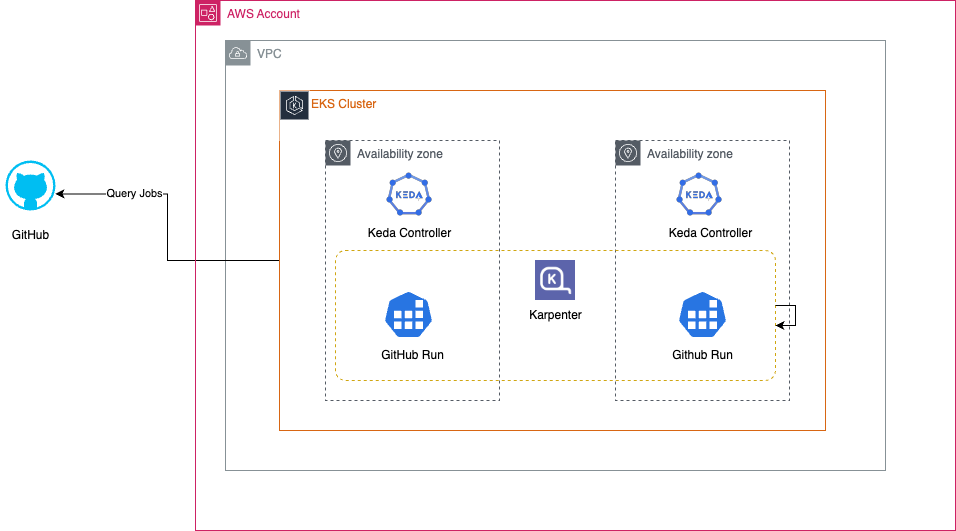
Kaltura’s initial solution deployed self-hosted GitHub Actions runners on Amazon EKS, using Karpenter for node auto-scaling. Kaltura implemented a custom controller that would poll the GitHub API for queued workflows and spin up necessary runners. While this solution provided the security and control Kaltura needed, it introduced substantial operational challenges.

The heart of the problems stemmed from Kaltura’s polling mechanism. As the solution’s scale grew, Kaltura frequently hit GitHub’s API rate limits, forcing a reduction of polling frequency to two-minute intervals. These circumstances created a cascading effect of operational issues. The DevOps teams spent considerable time maintaining runner images, infrastructure, and scaling mechanisms. Each new repository required manual configuration updates, creating bottlenecks in the development process. To meet performance SLAs, Kaltura maintained warm runner pools, significantly increasing infrastructure costs.

Architecture diagram showing Kaltura's initial CI/CD solution with GitHub repositories triggering workflows that are polled by a custom controller, which provisions GitHub Actions runners on Amazon EKS with Karpenter for auto-scaling, all operating within an Amazon VPC for secure access to internal resources

Figure 1: The initial solution was based on Amazon EKS and Karpenter spinning up GitHub Runners.

The impact on development teams was substantial. Every workflow execution faced a minimum two-minute delay between queuing and execution. These delays accumulated throughout the day, severely impacting developer productivity. The DevOps team found themselves constantly pulled away from other initiatives to handle infrastructure maintenance tasks. The situation became increasingly untenable as Kaltura continued to scale.

Kaltura’s Solution – AWS CodeBuild-hosted Runners

After evaluating several options, Kaltura chose CodeBuild-hosted runners to resolve infrastructure challenges while maintaining the security and control benefits of self-hosted solution. This new architecture fundamentally changed how the CI/CD solution operated, moving from a poll-based to a webhook-based system.

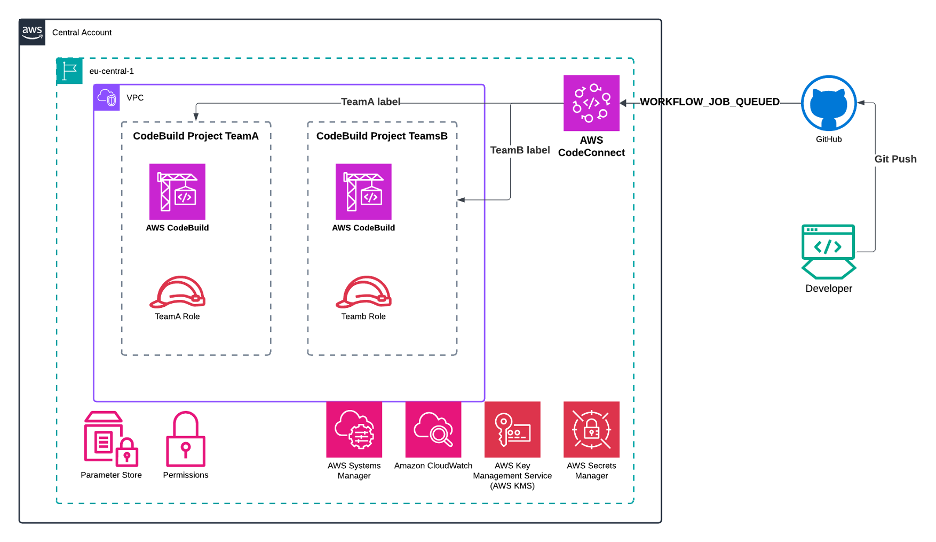
Architecture diagram showing Kaltura's modernized CI/CD solution using AWS CodeBuild-hosted runners, where GitHub repositories send webhook notifications through AWS CodeConnections to trigger CodeBuild, which provisions runners within an Amazon VPC with IAM role-based access to AWS services for executing GitHub Actions workflows.

Figure 2: The solution based on AWS CodeBuild is fully managed and is based on Webhooks.

The new architecture operates through a straightforward but powerful flow. When developers push code to GitHub, GitHub sends an immediate webhook notification to AWS CodeConnections. This triggers CodeBuild, which provisions a runner within Kaltura’s Amazon VPC. The GitHub Actions workflow then executes on this CodeBuild runner, leveraging fine-grained IAM roles that follow the principle of least privilege to access AWS services.

Key Architectural Components

The webhook-based architecture eliminates previous polling challenges entirely. Instead of waiting for a periodic check, workflows begin executing immediately when triggered. CodeBuild and CodeConnections use a GitHub App with webhooks, configurable at the repository, organization, or enterprise level. This integration allows true CI/CD auto-discovery, a significant advancement from previous manual configuration requirements.

Security remains one of the major components of the new architecture. Each runner operates within Amazon VPC, maintaining strict network security requirements. Kaltura implemented fine-grained access control through IAM roles, ensuring runners access only the specific AWS services they need, such as AWS Systems Manager Parameter Store, Amazon CloudWatch, and AWS Secrets Manager. This maintains security posture while simplifying access management.

Infrastructure Management

CodeBuild’s serverless nature transformed the infrastructure management approach. Rather than maintaining a complex Amazon EKS cluster with custom controllers and scaling logic, Kaltura now leverages AWS’s managed service. This shift eliminated the need to patch runner images, maintain infrastructure, or optimize scaling mechanisms.

The system’s flexibility proved particularly valuable for diverse workflow requirements. CodeBuild supports various compute configurations, from standard instances to multi-architecture builds and specialized ARM and GPU runners. Kaltura can easily match compute resources to workflow needs through simple label configurations, without managing different runner pools or maintaining separate infrastructure stacks.

Docker Workflow Improvements

One unexpected benefit emerged in Docker build processes. Previous Amazon EKS-based solutions required complex Docker-in-Docker (DinD) configurations or alternative tools like Kaniko for container builds. CodeBuild’s native Docker support eliminated these complications. The service provides isolated build environments where Docker can run directly, with built-in layer caching capabilities that significantly improve build performance.

Auto-Discovery and Self-Service

A key benefit of the new architecture is its self-service capability. When development teams create new repositories or modify existing ones, no manual DevOps intervention is required. The system automatically provisions appropriate runners based on predefined configurations and the workflow’s runs-on label. This self-service approach has dramatically reduced Kaltura’s operational overhead while improving developer productivity.

Here’s a typical workflow configuration demonstrating new approach:

name: Hello World

on: [push]

jobs:

  Hello-World-Job:

    runs-on:

      - codebuild-myProject-${{ github.run_id }}-${{ github.run_attempt }}

      - image:${{ matrix.os }}

      - instance-size:${{ matrix.size }}

      - fleet:myFleet

      - buildspec-override:true

    strategy:

      matrix:

        include:

          - os: arm-3.0

            size: small

          - os: linux-5.0

            size: large

    steps:

      - run: echo "Hello World!"

This configuration shows how Kaltura leverages CodeBuild’s flexibility while maintaining simple, declarative workflow definitions. Teams can specify their compute needs through labels, and the system handles all the underlying provisioning and management.

Migration Approach

The migration to CodeBuild runners involved a seamless transition with minimal workflow changes. The key to its successful migration was its simplicity – most workflows required only a single change to the runs-on label:

runs-on: codebuild-myProject-${{ github.run_id }}-${{ github.run_attempt }} 

Because of the 1-by-1 compatibility, it meant existing workflows continued to function without further modification.

Results

The new architecture successfully handles over 1,300 daily builds across more than 1,000 repositories and 100 workflow types while serving multiple development teams with varying security requirements. The results of the migration to CodeBuild-hosted runners delivered significant improvements across all key metrics:

Operational impact:

  • 90% reduction in DevOps operational overhead
  • 66% decrease in build queue times
  • 60% reduction in infrastructure costs
  • 30 minutes of daily time savings per developer

Most importantly, developer satisfaction has improved due to faster builds, reduced friction, and consistent performance. The self-service nature of the system has eliminated onboarding bottlenecks and accelerated the development lifecycle.

Conclusion

The transformation of Kaltura’s CI/CD infrastructure through CodeBuild-hosted runners demonstrates how modern cloud services solves complex enterprise-scale development challenges. The journey from managing self-hosted runners on Amazon EKS to leveraging AWS managed services delivered a 90% reduction in operational overhead, 66% faster build queues, and 60% cost savings while maintaining enterprise-grade security requirements.

For organizations considering a similar path, we recommend starting with a pilot program using non-critical repositories. Focus on understanding your workflow requirements, security needs, and performance bottlenecks to shape an effective migration strategy. Implement cost allocation tags and monitoring early to ensure visibility into the migration’s impact and demonstrate ROI to stakeholders.

Additional Resources:

About the Authors

Adi Ziv is a Senior Platform Engineer at Kaltura with over a decade of experience designing and building scalable, resilient, and optimized cloud-native applications and infrastructure. He specializes in serverless, containerized, and event-driven architectures.
MIchael Shapira photo Michael Shapira is a Senior Solution Architect at AWS specializing in Machine Learning and Generative AI solutions. With 19 years of software development experience, he is passionate about leveraging cutting-edge AI technologies to help customers transform their businesses and accelerate their cloud adoption journey. Michael is also an active member of the AWS Machine Learning community, where he contributes to innovation and knowledge sharing while helping customers scale their AI and cloud infrastructure at enterprise level. When he’s not architecting cloud solutions, Michael enjoys capturing the world through his camera lens as an avid photographer.
Maya Morav Freiman is a Technical Account Manager at AWS helping customers maximize value from AWS services and achieve their operational and business objectives. She is part of the AWS Serverless community and has 10 years experience as a DevOps engineer.

The content and opinions in this post are those of the third-party author and AWS is not responsible for the content or accuracy of this post.

Systemd v259 released

Post Syndicated from jzb original https://lwn.net/Articles/1051163/

Systemd
v259
has been released. Notable changes include a new
“--empower” option for run0 that provides elevated
privileges to a user without switching to root, ability to propagate a
user’s home directory into a VM with systemd-vmspawn, and
more. Support for System V service scripts has been deprecated, and
will be removed in v260. See the release notes for other changes,
feature removals, and deprecated features.

Security updates for Thursday

Post Syndicated from jzb original https://lwn.net/Articles/1051156/

Security updates have been issued by AlmaLinux (kernel, keylime, mysql:8.4, and tomcat), Debian (c-ares and webkit2gtk), Fedora (brotli, cups, golang-github-facebook-time, nebula, NetworkManager, perl-Alien-Brotli, python-django4.2, python-django5, and vips), Red Hat (binutils, buildah, curl, go-toolset:rhel8, golang, grafana, multiple packages, php:8.3, podman, python3.12, python39:3.9, ruby:3.3, and skopeo), SUSE (buildah, cups, firefox, glib2, grub2, helm, icinga-php-library, icingaweb2, ImageMagick, imagemagick, kernel, libpng12, libpng16, mariadb, openssl-3, poppler, python39, usbmuxd, webkit2gtk3, wireshark, and xkbcomp), and Ubuntu (linux-azure-fips).

Announcing support for GROUP BY, SUM, and other aggregation queries in R2 SQL

Post Syndicated from Jérôme Schneider original https://blog.cloudflare.com/r2-sql-aggregations/

When you’re dealing with large amounts of data, it’s helpful to get a quick overview — which is exactly what aggregations provide in SQL. Aggregations, known as “GROUP BY queries”, provide a bird’s eye view, so you can quickly gain insights from vast volumes of data.

That’s why we are excited to announce support for aggregations in R2 SQL, Cloudflare’s serverless, distributed, analytics query engine, which is capable of running SQL queries over data stored in R2 Data Catalog. Aggregations will allow users of R2 SQL to spot important trends and changes in the data, generate reports and find anomalies in logs.

This release builds on the already supported filter queries, which are foundational for analytical workloads, and allow users to find needles in haystacks of Apache Parquet files.

In this post, we’ll unpack the utility and quirks of aggregations, and then dive into how we extended R2 SQL to support running such queries over vast amounts of data stored in R2 Data Catalog.

The importance of aggregations in analytics

Aggregations, or “GROUP BY queries”, generate a short summary of the underlying data.

A common use case for aggregations is generating reports. Consider a table called “sales”, which contains historical data of all sales across various countries and departments of some organisation. One could easily generate a report on the volume of sales by department using this aggregation query:

SELECT department, sum(value)
FROM sales
GROUP BY department

The “GROUP BY” statement allows us to split table rows into buckets. Each bucket has a label corresponding to a particular department. Once the buckets are full, we can then calculate “sum(value)” for all rows in each bucket, giving us the total volume of sales performed by the corresponding department.

For some reports, we might only be interested in departments that had the largest volume. That’s where an “ORDER BY” statement comes in handy:

SELECT department, sum(value)
FROM sales
GROUP BY department
ORDER BY sum(value) DESC
LIMIT 10

Here we instruct the query engine to sort all department buckets by their total sales volume in the descending order and only return the top 10 largest.

Finally, we might be interested in filtering out anomalies. For example, we might want to only include departments that had more than five sales total in our report. We can easily do that with a “HAVING” statement:

SELECT department, sum(value), count(*)
FROM sales
GROUP BY department
HAVING count(*) > 5
ORDER BY sum(value) DESC
LIMIT 10

Here we added a new aggregate function to our query — “count(*)” — which calculates how many rows ended up in each bucket. This directly corresponds to the number of sales in each department, so we have also added a predicate in the “HAVING” statement to make sure that we only leave buckets with more than five rows in them.

Two approaches to aggregation: compute sooner or later

Aggregation queries have a curious property: they can reference columns that are not stored anywhere. Consider “sum(value)”: this column is computed by the query engine on the fly, unlike the “department” column, which is fetched from Parquet files stored on R2. This subtle difference means that any query that references aggregates like “sum”, “count” and others needs to be split into two phases.

The first phase is computing new columns. If we are to sort the data by “count(*)” column using “ORDER BY” statement or filter rows based on it using “HAVING” statement, we need to know the values of this column. Once the values of columns like “count(*)” are known, we can proceed with the rest of the query execution.

Note that if the query does not reference aggregate functions in “HAVING” or “ORDER BY”, but still uses them in “SELECT”, we can make use of a trick. Since we do not need the values of aggregate functions until the very end, we can compute them partially and merge results just before we are about to return them to the user.

The key difference between the two approaches is when we compute aggregate functions: in advance, to perform some additional computations on them later; or on the fly, to iteratively build results the user needs.

First, we will dive into building results on the fly — a technique we call “scatter-gather aggregations.” We will then build on top of that to introduce “shuffling aggregations” capable of running extra computations like “HAVING” and “ORDER BY” on top of aggregate functions.

Scatter-gather aggregations

Aggregate queries without “HAVING” and “ORDER BY” can be executed in a fashion similar to filter queries. For filter queries, R2 SQL picks one node to be the coordinator in query execution. This node analyzes the query and consults R2 Data Catalog to figure out which Parquet row groups may contain data relevant to the query. Each Parquet row group represents a relatively small piece of work that a single compute node can handle. Coordinator node distributes the work across many worker nodes and collects results to return them to the user.

In order to execute aggregate queries, we follow all the same steps and distribute small pieces of work between worker nodes. However, this time instead of just filtering rows based on the predicate in the “WHERE” statement, worker nodes also compute pre-aggregates.

Pre-aggregates represent an intermediary state of an aggregation. This is an incomplete piece of data representing a partially computed aggregate function on a subset of data. Multiple pre-aggregates can be merged together to compute the final value of an aggregate function. Splitting aggregate functions into pre-aggregates allows us to horizontally scale computation of aggregation, making use of vast compute resources available in Cloudflare’s network.


For example, pre-aggregate for “count(*)” is simply a number representing the count of rows in a subset of data. Computing the final “count(*)” is as easy as adding these numbers together. Pre-aggregate for “avg(value)” consists of two numbers: “sum(value)” and “count(*)”. The value of “avg(value)” can then be computed by adding together all “sum(value)” values, adding together all “count(*)” values and finally dividing one number by the other.

Once worker nodes have finished computing the pre-aggregates, they stream results to the coordinator node. The coordinator node collects all results, computes final values of aggregate functions from pre-aggregates, and returns the result to the user.

Shuffling, beyond the limits of scatter-gather

Scatter-gather is highly efficient when the coordinator can compute the final result by merging small, partial states from workers. If you run a query like SELECT sum(sales) FROM orders, the coordinator receives a single number from each worker and adds them up. The memory footprint on the coordinator is negligible regardless of how much data resides in R2.

However, this approach becomes inefficient when the query requires sorting or filtering based on the result of an aggregation. Consider this query, which finds the top two departments by sales volume:

SELECT department, sum(sales)
FROM sales
GROUP BY department
ORDER BY sum(sales) DESC
LIMIT 2

Correctly determining the global Top 2 requires knowing the total sales for every department across the entire dataset. Because the data is spread effectively at random across the underlying Parquet files, sales for a specific department are likely split across many different workers. A department might have low sales on every individual worker, excluding it from any local Top 2 list, yet have the highest sales volume globally when summed together.

The diagram below illustrates how a scatter-gather approach would not work for this query. “Dept A” is the global sales leader, but because its sales are evenly spread across workers, it doesn’t make to some local Top 2 lists, and ends up being discarded by the coordinator.


Consequently, when the query orders results by their global aggregation, the coordinator cannot rely on pre-filtered results from workers. It must request the total count for every department from every worker to calculate the global totals before it can sort them. If you are grouping by a high-cardinality column like IP addresses or User IDs, this forces the coordinator to ingest and merge millions of rows, creating a resource bottleneck on a single node.

To solve this, we need shuffling, a way to colocate data for specific groups before the final aggregation occurs.

Shuffling of aggregation data

To address the challenges of random data distribution, we introduce a shuffling stage. Instead of sending results to the coordinator, workers exchange data directly with each other to colocate rows based on their grouping key.

This routing relies on deterministic hash partitioning. When a worker processes a row, it hashes the GROUP BY column to identify the destination worker. Because this hash is deterministic, every worker in the cluster independently agrees on where to send specific data. If “Engineering” hashes to Worker 5, every worker knows to route “Engineering” rows to Worker 5. No central registry is required.

The diagram below illustrates this flow. Notice how “Dept A” starts on Workers 1, 2 and 3. Because the hash function maps “Dept A” to Worker 1, all workers route those rows to that same destination.


Shuffling aggregates produces the correct results. However, this all-to-all exchange creates a timing dependency. If Worker 1 begins calculating the final total for “Dept A” before Worker 3 has finished sending its share of the data, the result will be incomplete.

To address this, we enforce a strict synchronization barrier. The coordinator tracks the progress of the entire cluster while workers buffer their outgoing data and flush it via gRPC streams to their peers. Only when every worker confirms that it has finished processing its input files and flushing its shuffle buffers does the coordinator issue the command to proceed. This barrier guarantees that when the next stage begins, the dataset on each worker is complete and accurate.

Local finalization

Once the synchronization barrier is lifted, every worker holds the complete dataset for its assigned groups. Worker 1 now has 100% of the sales records for “Dept A” and can calculate the final total with certainty.

This allows us to push computational logic like filtering and sorting down to the worker rather than burdening the coordinator. For example, if the query includes HAVING count(*) > 5, the worker can filter out groups that do not meet this criteria immediately after aggregation.

At the end of this stage, each worker produces a sorted, finalized stream of results for the groups it owns.

The streaming merge

The final piece of the puzzle is the coordinator. In the scatter-gather model, the coordinator was responsible for the expensive task of aggregating and sorting the entire dataset. In the shuffling model, its role changes.

Because the workers have already computed the final aggregates and sorted them locally, the coordinator only needs to perform a k-way merge. It opens a stream to every worker and reads the results row by row. It compares the current row from each worker, picks the “winner” based on the sort order, and adds it to the query results that will be sent to the user.

This approach is particularly powerful for LIMIT queries. If a user asks for the top 10 departments, the coordinator merges the streams until it has found the top 10 items and then immediately stops processing. It does not need to load or merge the millions of remaining rows, allowing for greater scale of operation without over-consumption of compute resources.

A powerful engine for processing massive datasets

With the addition of aggregations, R2 SQL transforms from a tool great for filtering data into a powerful engine capable of data processing on massive datasets. This is made possible by implementing distributed execution strategies like scatter-gather and shuffling, where we are able to push the compute to where the data lives, using the scale of Cloudflare’s global compute and network. 

Whether you are generating reports, monitoring high-volume logs for anomalies, or simply trying to spot trends in your data, you can now easily do it all within Cloudflare’s Developer Platform without the overhead of managing complex OLAP infrastructure or moving data out of R2.

Try it now

Support for aggregations in R2 SQL is available today. We are excited to see how you use these new functions with data in R2 Data Catalog.

  • Get Started: Check out our documentation for examples and syntax guides on running aggregation queries.

  • Join the Conversation: If you have questions, feedback, or want to share what you’re building, join us in the Cloudflare Developer Discord.

 Introducing our new ‘Programming with AI’ unit

Post Syndicated from Rajib Sarkar original https://www.raspberrypi.org/blog/introducing-our-new-programming-with-ai-unit/

In the age of AI, we believe kids still need to learn to code. We’re also testing how AI tools can be used to help with teaching and learning programming. This blog dives into our new classroom unit ‘Programming with AI’, which we’ve developed for teachers to introduce students to learning to code using tools built on large language models (LLMs). We share an overview of the unit, and the early excitement of educators and learners with whom we’re exploring this new approach to teaching and learning programming.

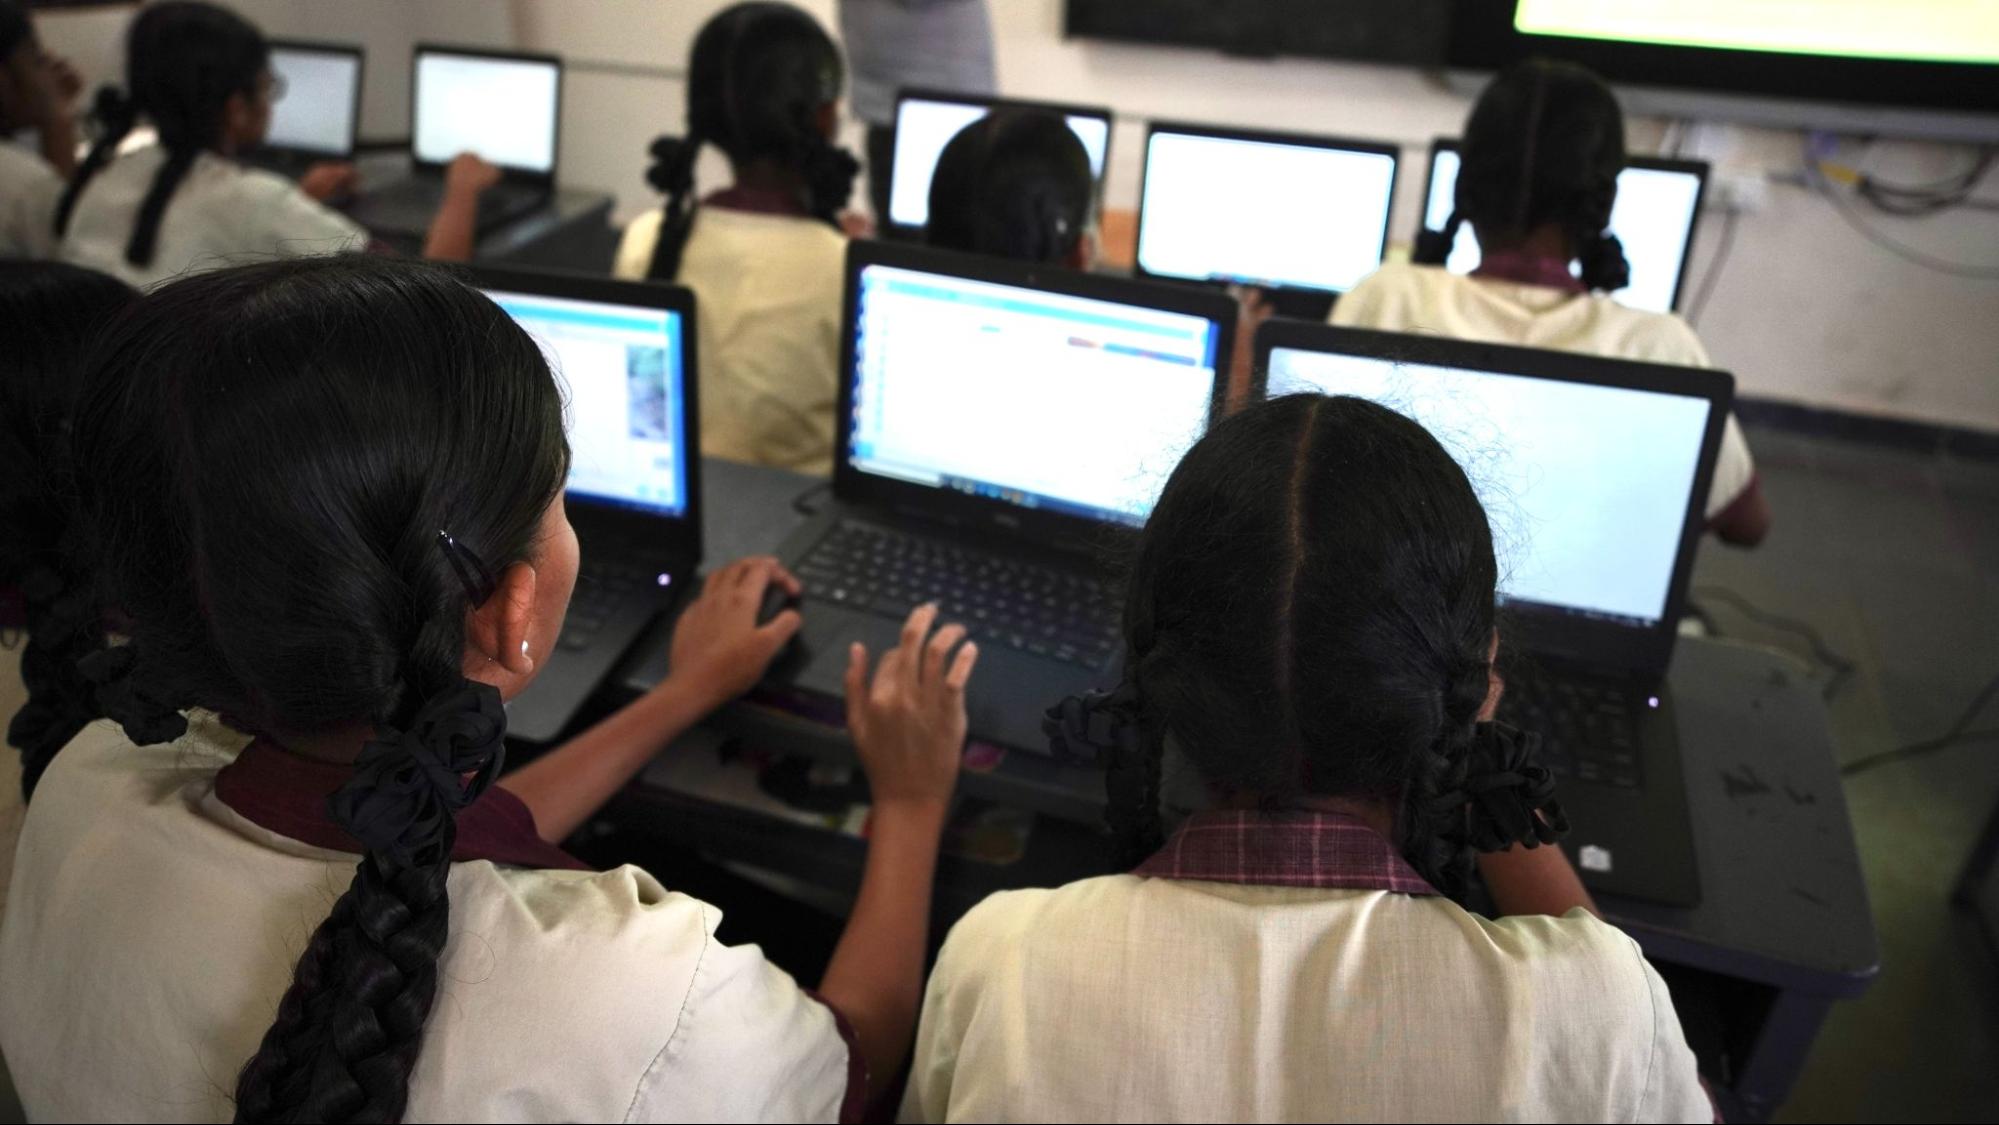
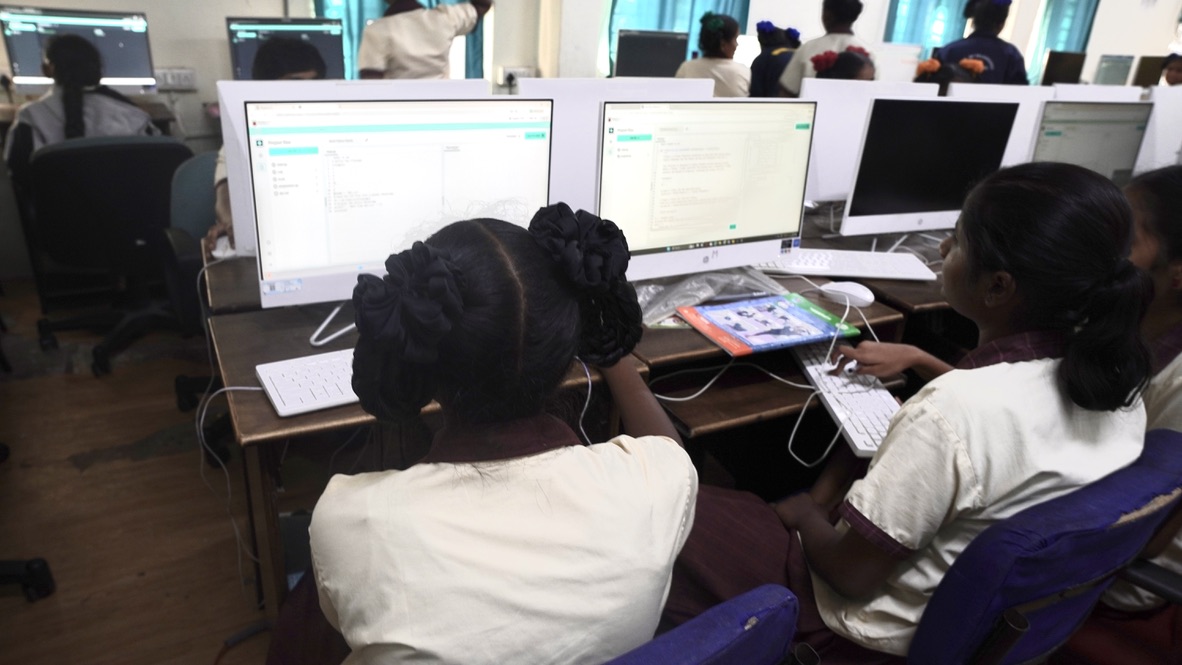
Students completing activities from lesson 1

Bridging the gap in programming education

As India is accelerating its efforts to modernise digital and computing education, it’s the ideal place for us to test how best to introduce learners to AI-assisted approaches to programming and teach them responsible AI use.

We decided to design a ‘Programming with AI’ unit of eight lessons that support students aged 14–16 to progress from block-based programming to text-based Python programming, Python being one of the most widely employed programming languages in industry and academia. In the new unit, students are guided to use LLM-based tools safely, ethically, and responsibly in order to undertake data analysis projects in Python. Students learn how to use the tools, such as Gemini and ChatGPT, to deepen their understanding, experiment with ideas, and connect classroom concepts with real-world technological applications.

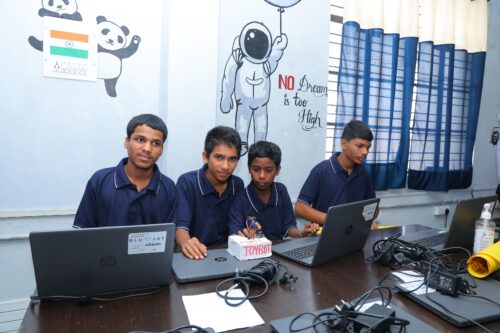
A group of male students at the Coding Academy in Telangana.

The ‘Programming with AI’ unit is currently being piloted across five residential schools under our partner, the Telangana Social Welfare Residential Educational Institutions Society. In the coming months, we will evaluate the impact of this AI-supported approach to learning programming on student engagement, motivation, and overall learning outcomes.

Key design decisions during unit development

During the design phase of the unit, we identified three main challenges we wanted to address:

  1. The first was the transition from block-based to text-based coding. The students we were designing for are familiar with block-based programming like Scratch, but Python needs precisely typed code (syntax). This is a huge shift, and we wanted to offer a way to bridge the gap.
  2. We also had to figure out how to teach prompting LLM tools to students who are learning English as their second language.
  3. Finally, LLMs are non-deterministic. This means that LLM tools don’t always produce the same output, even when given the same prompt. They also do not generate correct code consistently.

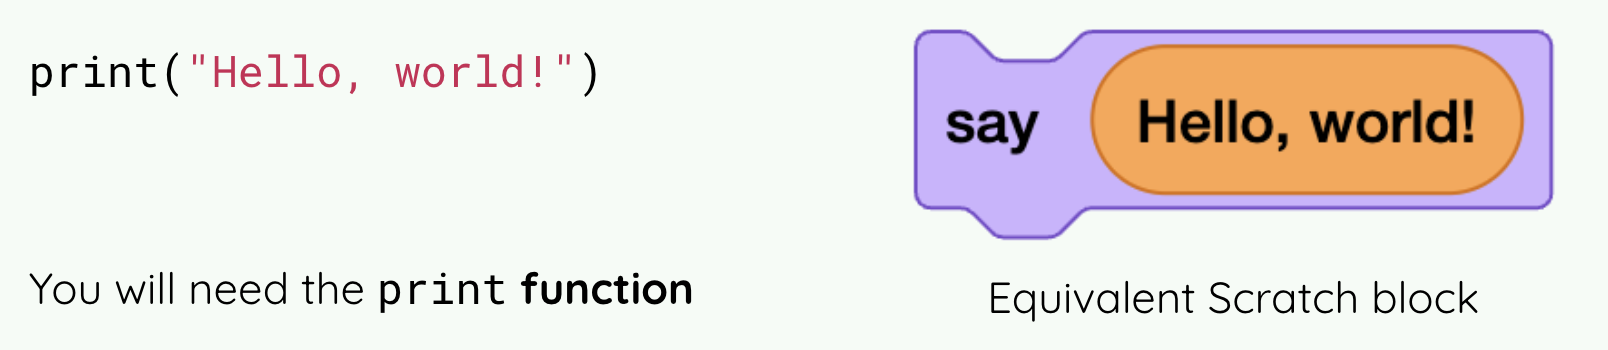
To solve the first problem, we decided that the initial lessons in the unit should start by showing familiar Scratch blocks right next to the equivalent Python syntax. This direct comparison makes the transition from block-based to text-based programmer smoother.

Comparison of Python syntax with equivalent Scratch block

To teach prompting, we built a gradual path. The unit starts with a debugging code activity, where students get code with errors and a prompt to make an LLM tool fix the errors. Later, they learn to break down a prompt into their goal (what output they want) and the context (additional information for the LLM tool). Eventually, they use a structured framework to prompt the tool to generate complete, bug-free code.

Handling the unpredictable outputs of LLM tools we turned into a learning activity. In one lesson, students are given different chatbot-generated code segments and asked to analyse and reflect on the code quality. This crucial exercise helps them build the critical thinking and code evaluation skills they need for programming with AI tools.

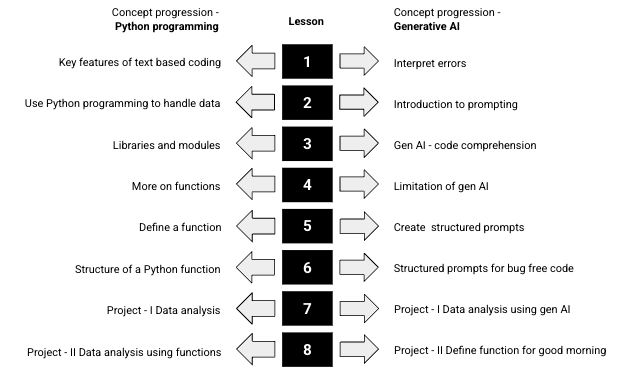
Illustration showing the progression of Python and generative AI concepts covered in the unit
The progression of Python and generative AI concepts covered in the unit

Over the eight lessons, there is a progression of Python concepts and generative AI concepts, as shown in the image above. They lead students to complete two challenging, real-world data analysis projects.

Preparing the educators

To ensure the successful pilot of the ‘Programming with AI’ unit, a comprehensive teacher training program was essential. We understood that teachers needed confidence and competence not only in the subject matter — programming — but also in guiding students to ethically and effectively use LLM tools.

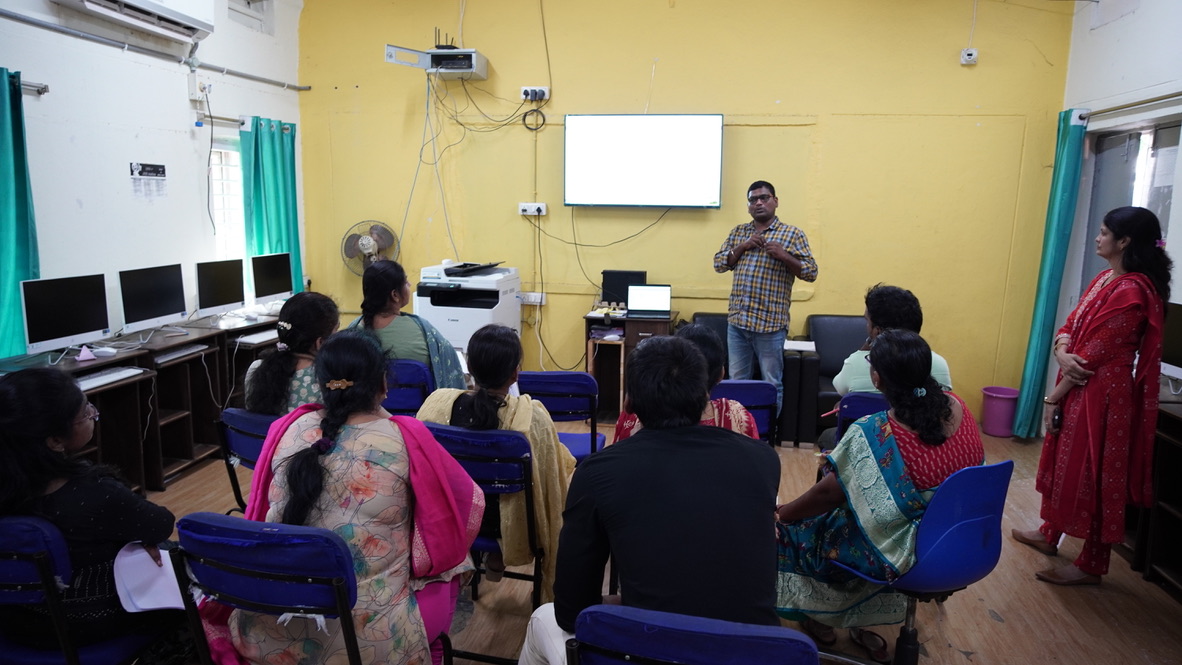
STEM and ICT teachers participated in the training

The training was an intensive, three-day programme: two days were held in-person for deep collaboration and one day was virtual for reinforcing key information. We covered five critical areas:

  • Hands-on activities to ensure comfort with the Python programming language
  • Exploring the capabilities and limitations of LLM tools
  • Effective prompt writing, which teachers would in turn model for their students to use for code debugging and idea generation
  • Reviewing lesson flow and learning objectives to understand the structure of a lesson
  • Adapting specific pedagogies to integrate an LLM tool in teaching the Python programming language

This training ensured our educators were not just teaching a new unit, but felt like confident facilitators ready to lead the shift towards AI-supported learning.

Initial student reactions: Excitement, familiarity with LLM tools, and seamless transition

The pilot of the ‘Programming with AI’ unit began during the second week of December 2025 across five selected schools. It was immediately met with enthusiastic student engagement — they were highly excited to learn Python programming using LLM tools.

When teachers initiated discussions about AI, students demonstrated their familiarity with LLMs, chatbots, and related concepts. They were not only aware of generative AI but could readily name and describe the functions of LLM tools, telling us they were actively using these tools to create projects in various other subjects.

Students could easily connect with the activities in the lessons as they had foundational understanding of programming, which they developed while learning block-based coding in Scratch. This prior knowledge enabled their seamless transition to the new learning. Perhaps most impressive was the students’ rapid adoption of LLM tools to debug their code. This skill can ease what is traditionally a steep learning curve when students first learn text-based programming.

We are now eagerly anticipating their curiosity and progress in the upcoming lessons.

Looking ahead and collecting impact data

With the initial enthusiasm confirmed, the pilot program moves into its next critical phase. Teachers will continue to deliver the unit over the next few months in the five selected schools in Telangana.

STEM and ICT teachers participated in the training
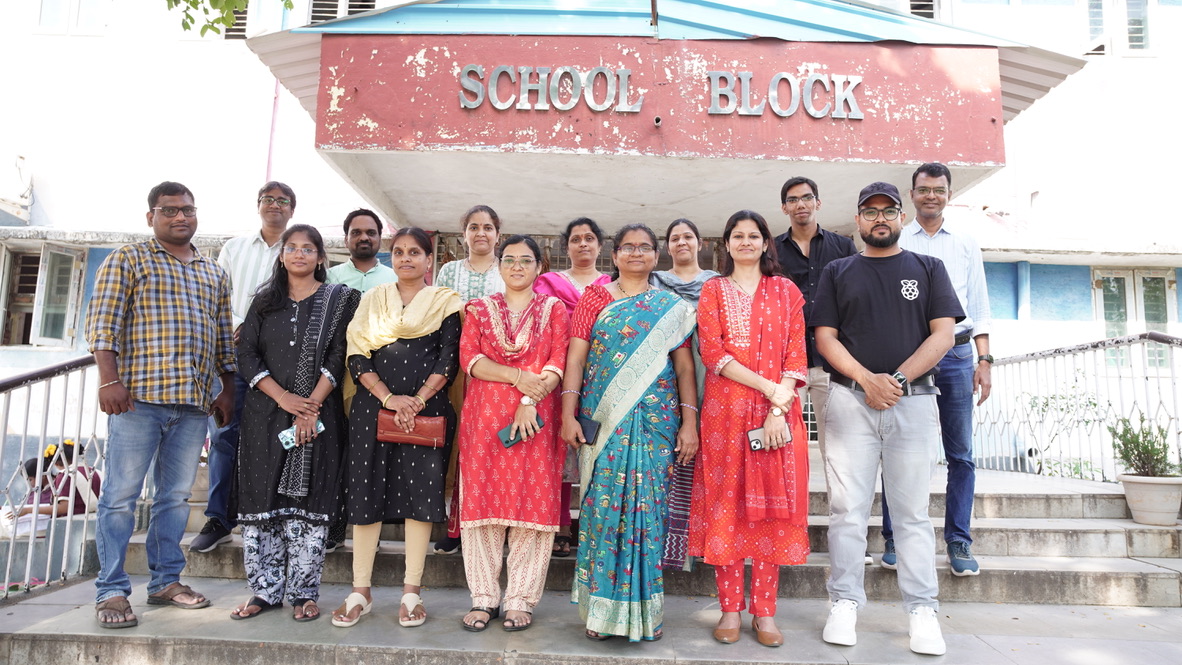
The teachers and team at our ‘Programming with AI’ training.

During this extended observation period, our primary focus will be on rigorous data collection and impact assessment. We will closely monitor how students interact with the provided learning materials and how they use LLM tools throughout the unit. We will systematically assess whether the new teaching approach successfully helps students achieve the defined learning objectives for Python programming. Crucially, we will capture comprehensive data to understand the impact of this AI-integrated approach on engagement, skill acquisition, and problem-solving compared to traditional methods.

Based on the synthesis and analysis of all the gathered data, we will share our gathered insights early next year. The findings will inform our plans for more widely introducing the AI-integrated unit and for developing similar content for other settings and age groups.

The post  Introducing our new ‘Programming with AI’ unit appeared first on Raspberry Pi Foundation.

Тоест разговаряме – епизод 5

Post Syndicated from Владислав Севов original https://www.toest.bg/toest-razgovaryame-epizod-5/

Тоест разговаряме – епизод 5

В „Тоест разговаряме“ със Светла Енчева обсъдихме многолюдните протести, довели до падането на правителството, споделихме вдъхновението от гражданската енергия, но и рационалните притеснения от възможностите за последващ „разцвет“ на евроскептични, антидемократични и проруски идеологии по унгарски/словашки модел.

Продължихме с темите, за които Светла пише в „Тоест“: правата на уязвимите и малцинствените групи, липсващата помощ за хората с деменция и техните близки, палиативните грижи за деца, интимния живот и достойнството на хората с увреждания, „женското лице“ на бедността, невидимите капани пред работещите майки и др. Светла говори за институционалната слепота и дехуманизацията, за хората, които „ги няма в списъка“, и за значението на личните истории, през които тези проблеми стават видими.

Засегнахме и правата на ЛГБТИ хората – включително нейната собствена биография и избора ѝ да не крие сексуалната си ориентация, цената на тази видимост и дългия списък с права, от които ЛГБТИ хората у нас са лишени. Говорихме и за медийната етика – от подхода „сълзичка – паричка“ до риалити формати като „Ергенът“, които нормализират насилие, унижение и сексизъм под маската на „забавление“.

Гледайте целия разговор в нашия YouTube канал:

Може да го чуете и като аудиозапис в SoundCloud:


На живо включихме и въпроси от публиката, но не успяхме пълноценно да отговорим на всички. Помолих Светла да допълни тук един от зрителските въпроси, а именно:

От какви основни права са лишени еднополовите двойки в България?

Освен от правата, произтичащи от конституционната забрана да сключват брак, и от тези, свързани с отглеждането на деца, хората в еднополови връзки в България умишлено биват лишавани и от други права. Едно от тях е правото на защита от домашно насилие – в Закона за защита от домашното насилие се прие дефиниция за интимна връзка, която включва само хетеросексуалните отношения. Така че според българското законодателство еднополовите двойки не само не можем да сключваме брак, а и връзките ни… не съществуват. Моята връзка например щастливо „не съществува“ вече 10 години.

Преди срещата ви помолихме да отговорите на кратката ни анкета. Ето и резултатите от нея:

Равните права са условие за достойно съществуване.


Светла Енчева е журналистка, редакторка и социоложка на свободна практика. Редовна авторка и редакторка е в „Тоест“, писала е и за „Свободна Европа“, „Маргиналия“ и други медии. Участвала е в множество изследователски проекти с фокус върху човешки права, уязвими групи, дискриминация, проблеми на жените и др. Завършила е философия, преподавала е социология и е активистка в областта на човешките права. Открито нехетеросексуална е и от 10 години е в щастлива връзка с жена.

Тоест разговаряме – епизод 5

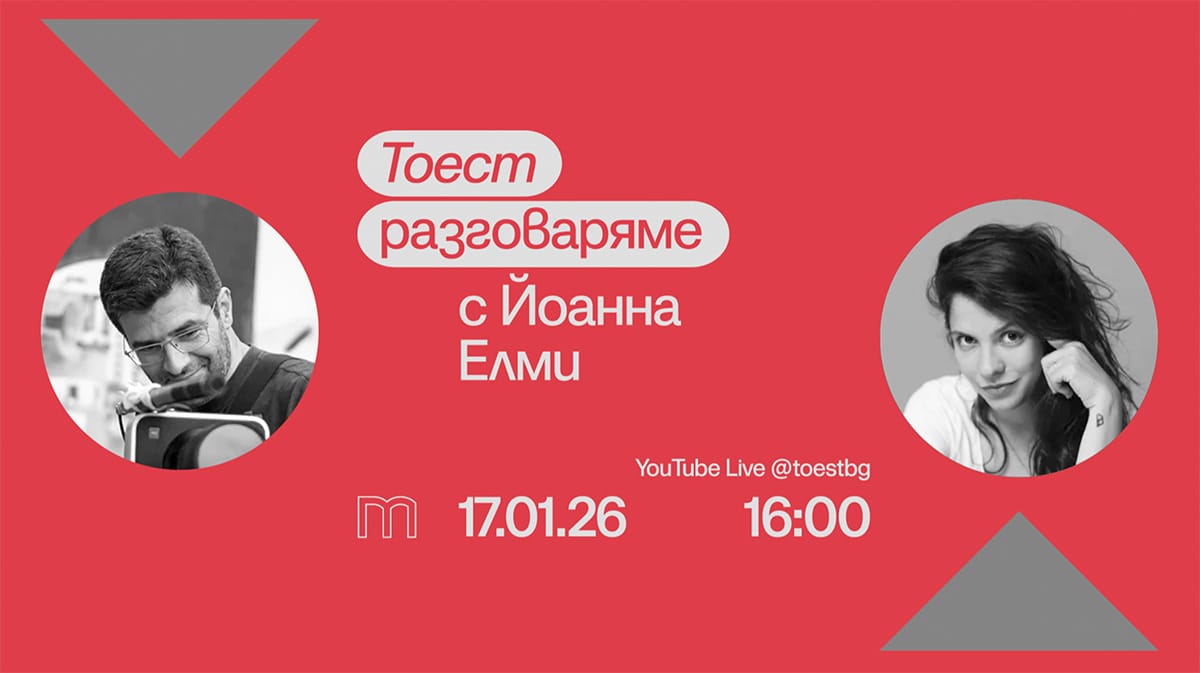
Следващата среща на „Тоест разговаряме“ ще бъде с Йоанна Елми, която е дългогодишна авторка на „Тоест“ и поддържа бюлетина „Гласовете на Америка“. Разговорът ще се излъчва на живо в YouTube Live на 17 януари, събота, от 16:00 ч.


В „Тоест разговаряме“ всеки месец ви срещаме с автори, които познавате добре от анализите или от рубриките им в „Тоест“, но този път ще ги видите и чуете в по-личен и непосредствен формат. Във видеоразговорите, предавани на живо, активно участие имате и вие, нашата публика – със своите въпроси, коментари и включване в тематичната анкета. Водещ на поредицата е Владислав Севов, дългогодишен телевизионен журналист и съосновател на „Тоест“.

Тоест разговаряме – епизод 5

„Тоест разговаряме“ е поредица, подкрепена от Институт „Отворено общество – София“ и съфинансирана от Европейския съюз в рамките на проекта Media Resilience. Изразените възгледи и мнения са само и изцяло на техните автори и не отразяват непременно възгледите и мненията на Европейския съюз, на Европейската изпълнителна агенция за образование и култура (EACEA) или на Институт „Отворено общество – София“ (ИООС). Нито Европейският съюз, нито EACEA, нито ИООС могат да бъдат държани отговорни за тях.

How Grab is accelerating growth with real-time personalization using Customer Data Platform scenarios

Post Syndicated from Grab Tech original https://engineering.grab.com/cdp-scenarios

Introduction

Delivering personalized user experiences in real-time is central to Grab’s strategy, but achieving this at scale poses significant engineering challenges. Grab’s Customer Data Platform (CDP) and Growth team has successfully delivered several real-time campaigns, driving significant business impact through enhanced personalization. These initiatives include high-impact use cases like immediate mall offers, timely traveler recommendations, precise ad retargeting, and proactive interventions during key user journey moments. At the core of these successes is Grab’s CDP, which rapidly deploys advanced real-time personalization via a powerful new capability called “Scenarios.”

About Grab’s CDP

Grab’s CDP is a centralized, reliable repository for user attributes, designed for freshness, governance, and reusability. Built on Grab’s Signal Marketplace framework, the CDP streamlines data management through automation and integration, supporting seamless interactions with internal services and toolings that power marketing, experimentation, ads, Machine Learning (ML) features, and external platforms, including Facebook, Google Ads, and TikTok.

The platform currently manages over 1,000 batch user attributes for Passengers, Drivers, and Merchants, powering diverse use cases from targeted marketing campaigns to operational decision-making across Grab’s entire ecosystem.

The need for real-time personalization

In our current CDP setup, user segments are primarily created for targeting using batch attributes that update once daily. While these batch updates provide valuable historical insights, they are not suitable for scenarios requiring real-time responsiveness. This delay prevents timely engagement with users, particularly when immediate actions can significantly enhance user experiences and conversion rates.

For example, when travelers land at an airport, they immediately benefit from timely suggestions for rides, dining options, or local attractions. Traditional batch processing cannot deliver the agility and responsiveness required for these dynamic scenarios.

Historically, real-time personalization at Grab relied heavily on engineering resources, which resulted in limited scalability and agility. Marketers and product teams often found themselves blocked by engineering bandwidth constraints, restricting experimentation and innovation.

Problem statement

The limitations of Grab’s existing personalization frameworks include:

  • Batch attribute delays: Daily updates are insufficient for scenarios requiring immediate user responses.

  • Limited dynamic enrichment: Difficulties in dynamically integrating real-time events with historical user data, weakens personalization effectiveness.

  • High engineering overhead: Custom solutions require extensive resources, limiting agility and innovation.

To overcome these challenges and support Grab’s vision for comprehensive personalization – including proactive recommendations and assistance – CDP needed robust real-time capabilities.

CDP Scenarios: Real-time personalization made simple

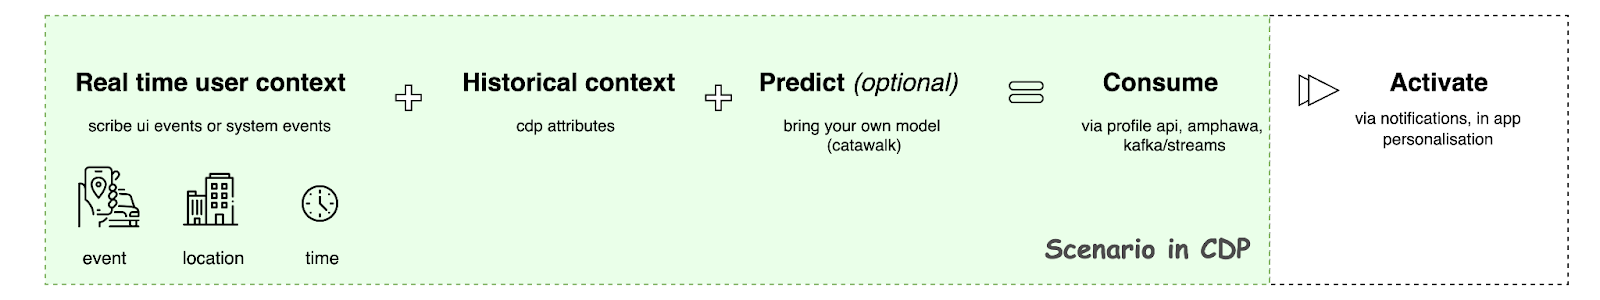
The Scenario feature revolutionizes real-time targeting within the CDP by utilizing user-initiated events, geo-fencing, historical profile data, and on-the-fly predictions. This empowers the business to deliver easy, quick, and flexible personalization without the need for complex engineering efforts.

Scenarios enable innovative use cases such as these:

  • Mall personalization: Real-time personalized offers upon arrival.
  • Traveler assistance: Immediate recommendations at airports or hotels.
  • Ad retargeting: Enhanced real-time ad targeting.
  • Conversion optimization: Timely intervention during user drop-off points.

Imagine predicting a user’s intent to drop off at a mall using both real-time and historical context. For instance, when a user books a ride to a mall, factors such as destination, time, cuisine preferences, and past behavior (e.g., affluence level) can help predict whether the user’s purpose is retail therapy, grocery shopping, or dining out. This prediction accounts for elements like time of day, day of the week, and mall location. Grab’s engineering teams can leverage this predicted intent (signal) to offer personalized actions, such as GrabPay discounts for shopping or exclusive dining offers for dinner.

Figure 1. Scenario in CDP.

Key features

  • Event-driven personalization: Real-time Scenarios triggered by Scribe events (Grab’s comprehensive event collection and tracking platform) combined with geo-fencing.
  • Historical context integration: Optionally enrich Scenarios using historical CDP data.
  • Predictive modeling: Deploy pre-trained models for instant user behavior predictions.
  • Self-serve graphical user interface (GUI): Enable marketers to create complex event sequences and validate Scenarios with synthetic data processed through Flink pipelines.
  • Headless application programming interfaces (APIs): Allow programmatic access and management of Scenarios.
Figure 2. Attributes for a scenario in CDP.

Self-serve Scenario creation

We designed an intuitive self-serve UI, embedded within the Grab app, empowering marketers to quickly define and deploy Scenarios. Users can specify event triggers, configure geo-fencing, incorporate historical user attributes, and select predictive models. Marketers can also validate Scenarios using synthetic data before deployment, ensuring accurate and realistic outcomes.

How it works:

  1. Select event triggers: Choose predefined events or define custom intra-session sequences via the GUI.
  2. Configure geo-fencing: Define Scenario activation locations, like airports or malls.
  3. Include historical attributes (optional): Utilize batch attributes from the CDP to enrich Scenarios.
  4. Select predictive models (optional): Train custom classifiers or pick from pre-trained Catwalk models.
  5. Define data sink: Choose between Amphawa (DynamoDB), Kafka, or both; potentially extendable to external destinations (e.g., Appsflyer).
  6. Once configured, metadata synchronizes automatically with our streaming service, and Scenarios become available for real-time consumption within an hour.

Proven impact: Real-world success

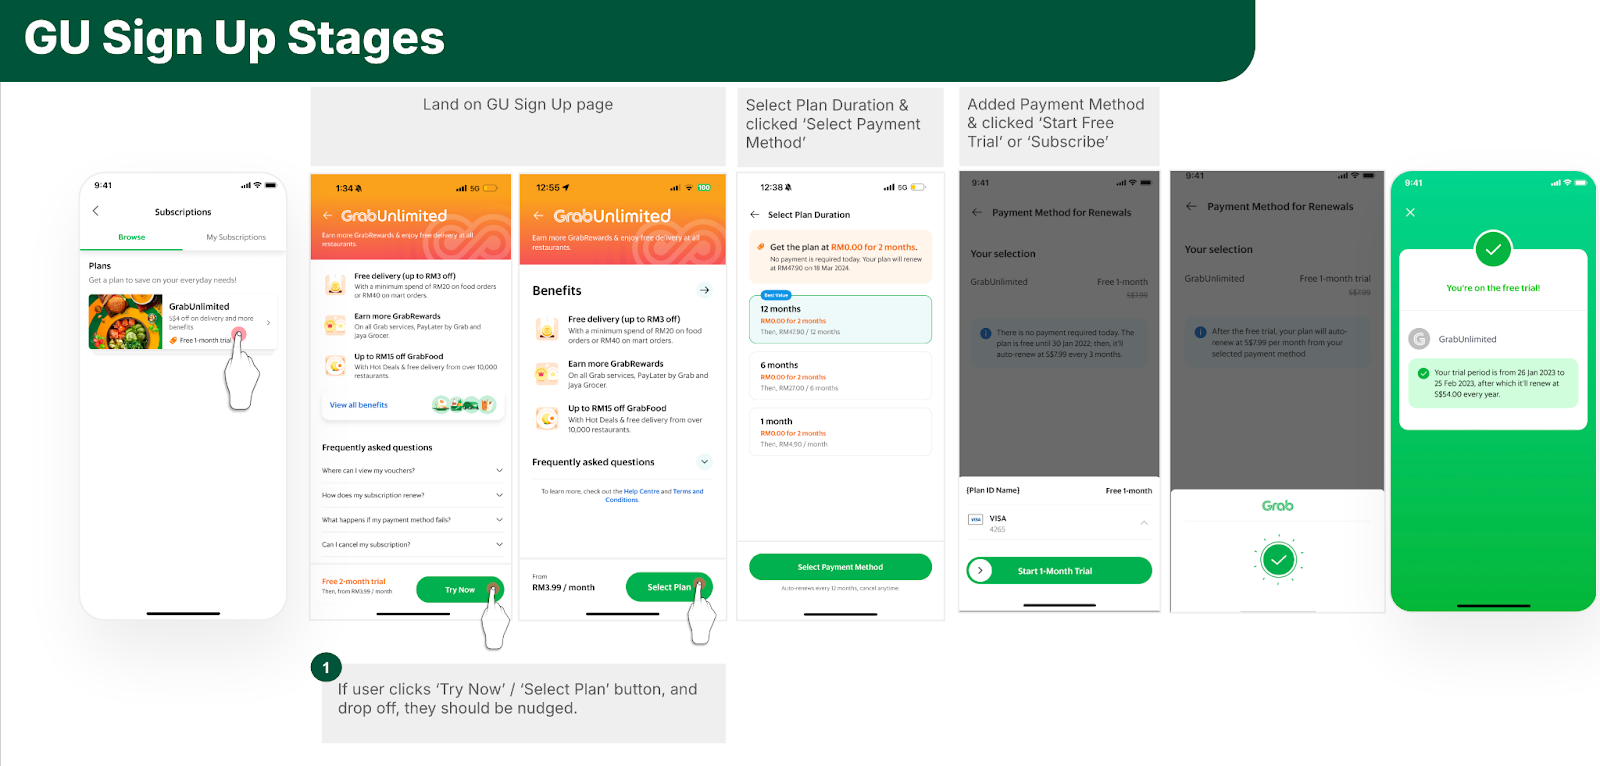
CDP Scenarios are already delivering measurable business results, with over 12 live production implementations. For instance, in a case study addressing Grab Unlimited subscription signup abandonment, we leveraged CDP Scenarios to increase signups by engaging users in real time within 15 minutes of them leaving the signup process.

Figure 3. Grab Unlimited sign-up journey.

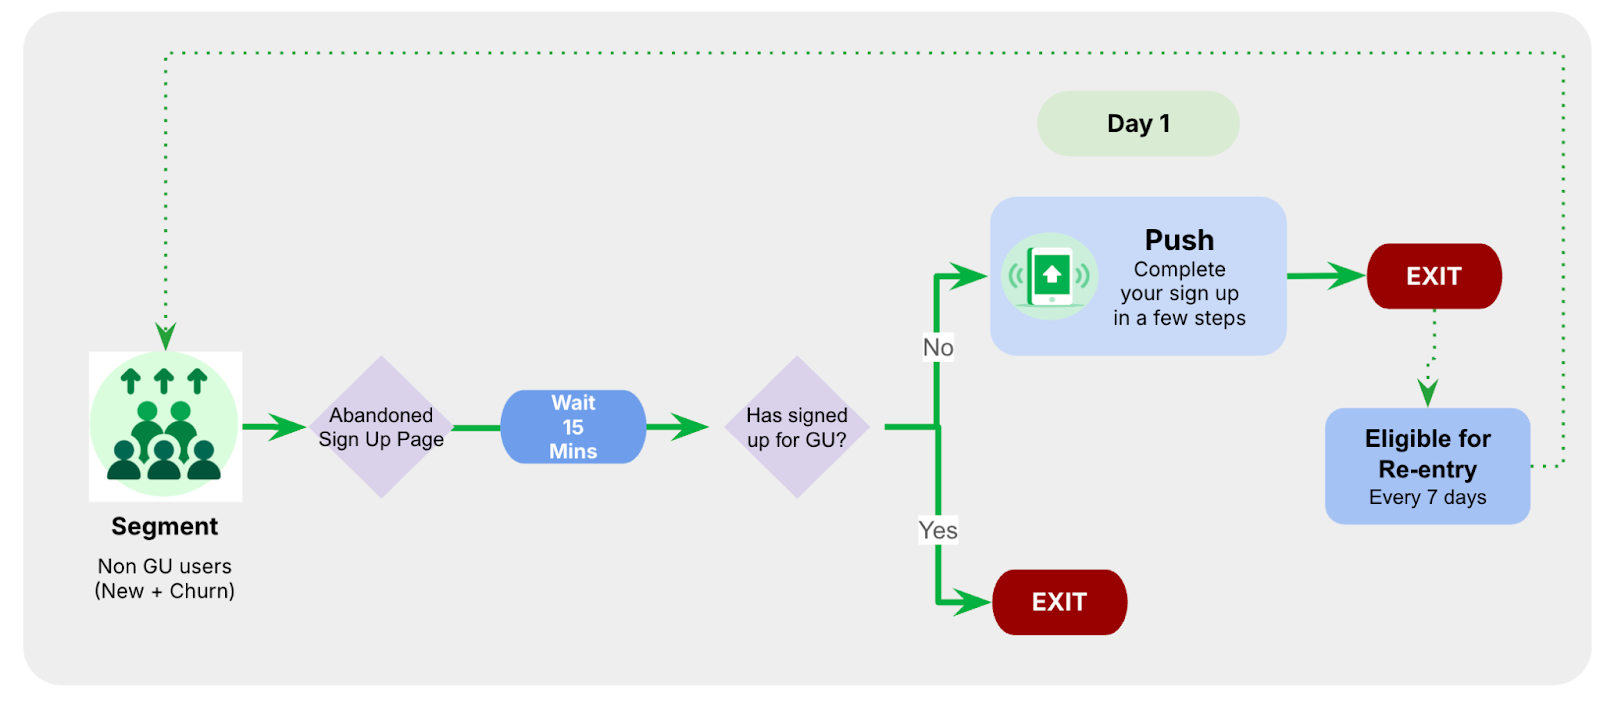
To enhance conversion rates, personalized real-time nudges were deployed through Scenarios. For example, users who started the signup process but failed to complete it within 15 minutes received a follow-up notification, prompting them to finalize their registration.

Figure 4. Scenario flow for Grab Unlimited registration.

This scenario alone achieved more than a 3% uplift in subscriber conversions vs non-real-time acquisition campaigns, demonstrating Scenarios’ potential to significantly boost business outcomes.

Technical architecture: Low latency, high reliability

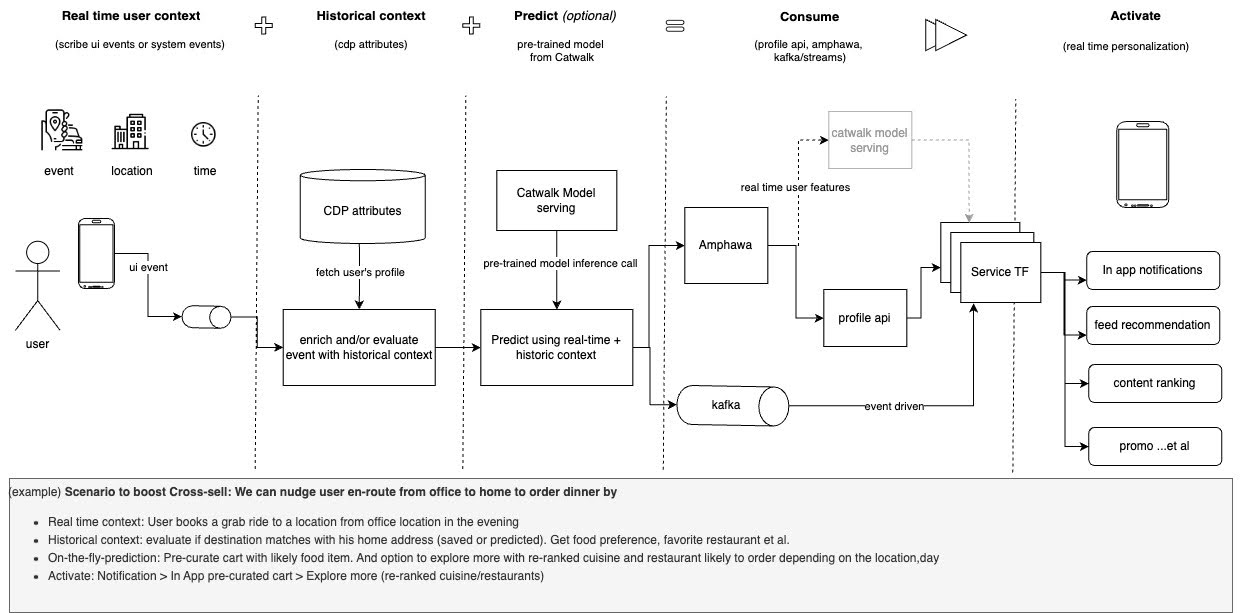
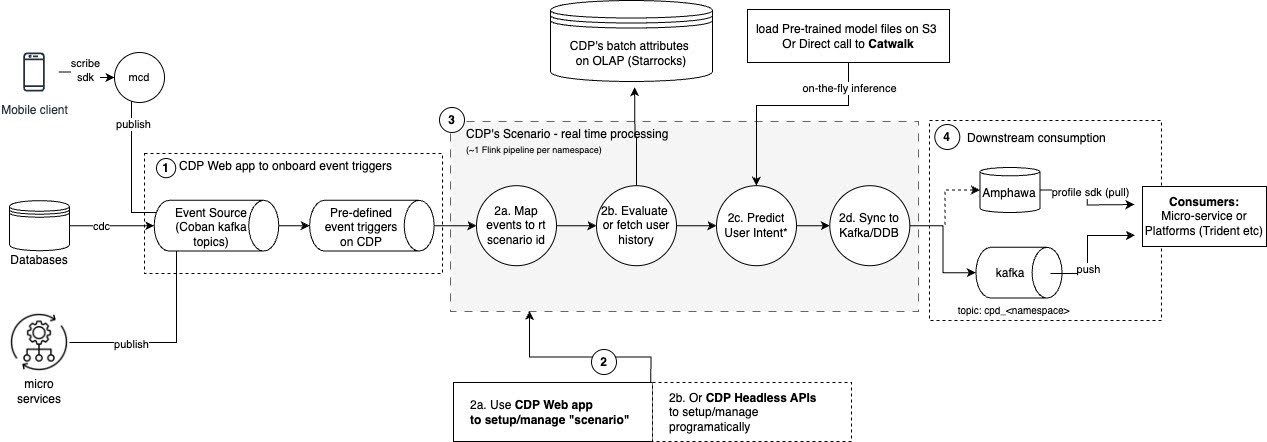
Figure 5. High-level scenario flow. Scenarios are designed for low latency (under 15 seconds) and high reliability.
  1. Event registration: Popular UI events from Scribe are whitelisted and immediately available; custom events are onboarded via the CDP web portal.
  2. Scenario creation: Users configure Scenarios through a user-friendly GUI, defining events, historical contexts, and predictive models.
  3. Real-time Flink processing: Incoming events trigger Scenarios, evaluating user historical data via StarRocks and performing real-time predictions using pre-trained models.
  4. Real-time data sync: Outcomes are synced back to Kafka or Amphawa (Grab’s internal feature store built on AWS DynamoDB), enriching data for use by subsequent services.
  5. Consumption by downstream services: Kafka streams or CDP’s Profile SDK facilitates immediate, personalized user experiences.

Advancing the future of real-time personalization

As we continue to innovate, we are focused on enhancing the capabilities of CDP Scenarios to support more complex and scalable personalization use cases. Here are some key areas of improvement we are exploring:

  • Optimized Scenario sharding for scalable processing: To accommodate the growing number of use cases, we plan to scale and orchestrate our Flink pipeline fleet in a headless manner. This approach will improve system stability and enable seamless management of complex Scenarios across the pipeline.

  • Enhanced signal distribution across multiple destinations: Currently, Scenario outputs are limited to a single topic or sink. To address the increasing diversity of use cases, we aim to expand signal distribution, allowing downstream consumers to access Scenario outcomes through multiple scalable and reliable channels.

  • Advanced scheduling and delayed triggering: While real-time computation of Scenario signals is effective, certain use cases require delayed activation for maximum impact. We are exploring ways to compute signals instantly but trigger actions at scheduled times, such as sending a push notification for booking a return Grab ride based on the average wait time at the drop-off location.

Conclusion: Revolutionizing real-time personalization

The launch of CDP Scenarios represents a significant milestone for Grab, paving the way for scalable, efficient, and user-friendly real-time personalization. Initial successes have demonstrated its immense potential, delivering notable improvements in user engagement and conversion rates. Looking ahead, we are committed to continuously advancing Scenarios by expanding its features, integrations, and applications to further elevate user experiences across the Grab ecosystem.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people everyday to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

[$] LWN.net Weekly Edition for December 18, 2025

Post Syndicated from corbet original https://lwn.net/Articles/1049996/

Inside this week’s LWN.net Weekly Edition:

  • Front: Civil Infrastructure Platform; COSMIC desktop; Calibre adds AI; Maintainer’s Summit; ML tools for kernel development; linux-next; Rust in the kernel; kernel development tools; Linux process improvements; 6.19 merge window part 2.
  • Briefs: capsudo; Asahi Linux 6.18; Pop!_OS 24.04; Vojtux; KDE Gear 25.12; Rust 1.92.0; Quotes; …
  • Announcements: Newsletters, conferences, security updates, patches, and more.

NVIDIA ConnectX-8 C8240 800G Dual 400G NIC Review This is a SuperNIC

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/nvidia-connectx-8-dual-400gbe-400g-nic-review/

In our NVIDIA ConnectX-8 SuperNIC review, we show full next-gen 800G performance from the C8240 dual 400GbE card in PCIe Gen5 servers

The post NVIDIA ConnectX-8 C8240 800G Dual 400G NIC Review This is a SuperNIC appeared first on ServeTheHome.

Security Hub CSPM automation rule migration to Security Hub

Post Syndicated from Joe Wagner original https://aws.amazon.com/blogs/security/security-hub-cspm-automation-rule-migration-to-security-hub/

A new version of AWS Security Hub is now generally available with new capabilities to aggregate, correlate, and contextualize your security alerts across Amazon Web Services (AWS) accounts. The prior version is now known as AWS Security Hub CSPM and will continue to be available as a unique service focused on cloud security posture management and finding aggregation.

One capability available in both services is automation rules. In both Security Hub and Security Hub CSPM, you can use automation rules to automatically update finding fields when the criteria they define are met. In Security Hub, automation rules can be used to send findings to third-party platforms for operational response. Many existing Security Hub CSPM users have automation rules for tasks such as elevating the severity of a finding because it affects a production resource or adding a comment to assist in remediation workflows. While both services offer similar automation rule functionality, rules aren’t synchronized across the two services. If you are an existing Security Hub CSPM customer looking to adopt the new Security Hub, you might be interested in migrating the automation rules that have already been built. This helps keep your automation rules processing close to where you’re reviewing findings. As of publication, this capability is included in the cost of the Security Hub essentials plan. For current pricing details, refer to the Security Hub pricing page.

This post provides a solution to automatically migrate automation rules from Security Hub CSPM to Security Hub, helping you maintain your security automation workflows while taking advantage of the new Security Hub features. If you aren’t currently using automation rules and want to get started, see Automation rules in Security Hub.

Automation rule migration challenge

Security Hub CSPM uses the AWS Security Finding Format (ASFF) as the schema for its findings. This schema is fundamental to how automation rules are applied to findings as they are generated. Automation rules begin by defining one or more criteria and then selecting one or more actions that will be applied when the specified criteria are met. Each criterion specifies an ASFF field, an operator (such as equals or contains), and a value. Actions then update one or more ASFF fields.

The new version of Security Hub uses the Open Cybersecurity Schema Framework (OCSF), a widely adopted open-source schema supported by AWS and partners in the cybersecurity industry. Security Hub automation rules structurally work the same way as Security Hub CSPM rules. However, the underlying schema change means existing automation rules require transformation.

The solution provided in this post automatically discovers Security Hub CSPM automation rules, transforms them into the OCSF schema, and creates an AWS CloudFormation template that you can use to deploy them to your AWS account running the new version of Security Hub. Because of inherent differences between the ASFF and OCSF schemas, some rules can’t be automatically migrated, while others might require manual review after migration.

The following table show the current mapping between ASFF fields supported as criteria and their corresponding OCSF fields. These mappings may change in future service releases. Fields marked as N/A can’t be migrated and will require special consideration when migrating automation rules. They need to be redesigned in the new Security Hub. The solution provided in this post is designed to skip migration of rules with one or more ASFF criteria that don’t map to an OCSF field but will identify those rules in a report for your review.

Rule criterion in ASFF Corresponding OCSF field
AwsAccountId cloud.account.uid
AwsAccountName  cloud.account.name
CompanyName  metadata.product.vendor_name 
ComplianceAssociatedStandardsId compliance.standards
ComplianceSecurityControlId  compliance.control 
ComplianceStatus  compliance.status 
Confidence  confidence_score
CreatedAt  finding_info.created_time 
Criticality  N/A
Description  finding_info.desc 
FirstObservedAt  finding_info.first_seen_time
GeneratorId  N/A
Id  finding_info.uid 
 LastObservedAt finding_info.last_seen_time 
 NoteText comment 
NoteUpdatedAt  N/A
NoteUpdatedBy  N/A
ProductArn  metadata.product.uid 
ProductName  metadata.product.name 
RecordState  activity_name 
RelatedFindingsId  N/A
RelatedFindingsProductArn  N/A
ResourceApplicationArn  N/A
ResourceApplicationName  N/A
ResourceDetailsOther  N/A
ResourceId  resources[x].uid 
ResourcePartition  resources[x].cloud_partition 
ResourceRegion  resources[x].region 
ResourceTags  resources[x].tags 
ResourceType  resources[x].type 
SeverityLabel  vendor_attributes.severity 
SourceUrl  finding_info.src_url 
Title  finding_info.title 
Type  finding_info.types 
UpdatedAt  finding_info.modified_time 
UserDefinedFields  N/A
VerificationState  N/A
WorkflowStatus  status 

The following table shows the ASFF fields that are supported as actions and their corresponding OCSF fields. Note that several action fields aren’t available in OCSF:

Rule action fields in ASFF Corresponding OCSF field
Confidence  N/A
Criticality  N/A
Note  Comment 
RelatedFindings  N/A
Severity  Severity 
Types  N/A
UserDefinedFields  N/A
VerificationState  N/A
Workflow Status  Status 

For Security Hub CSPM automation rules that include actions without OCSF equivalents, the solution is designed to migrate the rules but include only the supported actions. These rules will be designated as partially migrated in the rule description and the migration report. You can use this information to review and modify the rules before enabling them, helping to ensure that the new automation rules behave as expected.

Solution overview

This solution provides a set of Python scripts designed to assist with the migration of automation rules from Security Hub CSPM to the new Security Hub. Here’s how the migration process works:

  1. Begin migration: The solution provides an orchestration script that initiates three sub-scripts and manages passing the proper inputs to them.
  2. Discovery: The solution scans your Security Hub CSPM environment to identify and collect existing automation rules across specified AWS Regions.
  3. Analysis: Each rule is evaluated to determine if it can be fully migrated, partially migrated, or requires manual intervention based on ASFF to OCSF field mapping compatibility.
  4. Transformation: Compatible rules are automatically converted from the ASFF schema to the OCSF schema using predefined field mappings.
  5. Template creation: The solution generates a CloudFormation template containing the transformed rules, maintaining their original order and Regional context.
  6. Deployment: Review the generated template and deploy it to create the migrated rules in Security Hub, where they are created in a disabled state by default.
  7. Validate and enable rules: Review each migrated rule in the AWS Management Console for Security Hub to verify its criteria, actions, and preview your current matching findings if applicable. After confirming that the rules work as intended individually and as a sequence, enable them to resume your automation workflows.
Figure 1: Architecture diagram showing scripts and how they interact with AWS

Figure 1: Architecture diagram showing scripts and how they interact with AWS

The solution, shown in Figure 1, consists of four Python scripts that work together to migrate your automation rules:

  1. Orchestrator: Coordinates discovery, transformation, and generation along with reporting and logging
  2. Rule discovery: Identifies and extracts existing automation rules from Security Hub CSPM across the Regions you specify
  3. Schema transformation: Converts the rules from ASFF to OCSF format using the field mapping detailed earlier
  4. Template generation: Creates CloudFormation templates that you can use to deploy the migrate rules

The scripts use credentials configured using the AWS Command Line Interface (AWS CLI) to discover existing Security Hub automation rules. For details on how to configure credentials using AWS CLI, see Setting up the AWS CLI.

Prerequisites

Before running the solution, ensure you have the following components and permissions in place.

  • Required software:
    • AWS CLI (latest version)
    • Python 3.12 or later
    • Python packages:
      • boto3 (latest version)
      • pyyaml (latest version)
  • Required permissions:
    For rule discovery and transformation:

    • securityhub:ListAutomationRules
    • securityhub:BatchGetAutomationRules
    • securityhub:GetFindingAggregator
    • securityhub:DescribeHub
    • securityhub:ListAutomationRulesV2

    For template deployment:

    • cloudformation:CreateStack
    • cloudformation:UpdateStack
    • cloudformation:DescribeStacks
    • cloudformation:CreateChangeSet
    • cloudformation:DescribeChangeSet
    • cloudformation:ExecuteChangeSet
    • cloudformation:GetTemplateSummary
    • securityhub:CreateAutomationRuleV2
    • securityhub:UpdateAutomationRuleV2
    • securityhub:DeleteAutomationRuleV2
    • securityhub:GetAutomationRuleV2
    • securityhub:TagResource
    • securityhub:ListTagsForResource

AWS account configuration

Security Hub supports a delegated administrator account model when used with AWS Organizations. This delegated administrator account centralizes the management of security findings and service configuration across your organization’s member accounts. Automation rules must be created in the delegated administrator account in the home Region, and in unlinked Regions. Member accounts can’t create their own automation rules.

We recommend using the same account as the delegated administrator for Security Hub CSPM and Security Hub to maintain consistent security management. Configure your AWS CLI with credentials for this delegated administrator account before running the migration solution (see Setting up the AWS CLI for more information).

While this solution is primarily designed for delegated administrator deployments, it also supports single-account Security Hub implementations.

Key migration concepts

Before proceeding with the migration of your automation rules from Security Hub CSPM to Security Hub, it’s important to understand several key concepts that affect how rules are migrated and deployed. These concepts influence the migration process and the resulting behavior of your rules. Understanding them will help you plan your migration strategy and validate the results effectively.

Default rule state

By default, migrated rules are created in a DISABLED state, meaning the actions will not be applied to findings as they are generated. The solution can optionally create rules in an ENABLED state, but this is not recommended. Instead, create the rules in a DISABLED state, review each rule, preview matching findings, and then move the rule to an ENABLED state when ready.

Unsupported fields

The migration report details any rules that can’t be migrated because they include one or more Security Hub CSPM criteria that aren’t supported by the new Security Hub. These cases occur because of the differences between the ASFF and OCSF schemas. These rules require special attention because they can’t be automatically replicated with equivalent behavior. This is particularly important if you have Security Hub CSPM rules that depend on priority order.

When rules have actions that aren’t supported, they will still be migrated if at least one action is supported. Rules with partially supported actions are flagged in the migration report and the new automation rule description and should be reviewed.

Home and linked Regions

Both Security Hub CSPM and Security Hub support a home Region that aggregates findings from linked Regions. However, their automation rules behave differently. Security Hub CSPM automation rules operate on a Regional basis. This means they only affect findings generated in the Region where they are created. Even if you use a home Region, Security Hub CSPM automation rules do not apply to the findings aggregated from linked Regions in the home Region. Security Hub supports automation rules defined in a home Region and applied to all linked Regions, and does not support the creation of automation rules in linked Regions. However, in Security Hub, unlinked Regions can still have their own automation rules that will affect only the findings generated in that Region. Unlinked Regions will need to have automation rules applied separately

The solution supports two deployment modes to handle these differences. The first mode, called Home Region, should be used for Security Hub deployments with a home Region enabled. This mode identifies Security Hub CSPM automation rules from specified Regions and then recreates them with an additional criteria to account for the Region the rule came from. Then, one CloudFormation template is generated that can be deployed in the home Region. The automation rules will still operate as intended because of the addition of the criteria for the original Region where it was created.

The second mode is called Region-by-Region. This mode is for users who don’t currently use a home Region. In this mode, the solution still discovers automation rules in the Regions specified but generates a unique CloudFormation template for each Region. The resulting templates can then be deployed one by one to the delegated administrator account for their corresponding Region. No additional criteria are added to the automation rule in this mode.

It is possible to use a home Region with Security Hub and link some Regions, but not all. If this is the case, run the Home Region mode for the home Region and all linked Regions. Then, re-run the solution in Region-by-Region mode for all unlinked Regions.

Rule order

Both Security Hub CSPM and Security Hub automation rules have an order in which they are evaluated. This can be important for certain situations where different automation rules might apply to the same findings or take actions on the same fields. This solution preserves the original order of your automation rules.

If there are existing Security Hub automation rules, the solution creates the new automation rules beginning after the existing rules. For example, if you have 3 Security Hub automation rules and are migrating 10 new rules, the solution will assign orders 4 through 13 to the new rules.

When using the Home Region mode, the order of automation rules for each Region is preserved and clustered together in the final order. For example, if a user with three Security Hub automation rules in three different Regions migrates the rules, they will be migrated sequentially. The solution will first migrate all rules from Region 1 in their original order, followed by all rules from Region 2 in their original order, and finally all rules from Region 3 in their original order.

Deploy and validate the migration

Now that you have the prerequisites in place and understand the basic concepts, you’re ready to deploy and validate the migration.

To deploy the migration:

1. Clone the Security Hub automation rules Migration Tool from the AWS samples GitHub repository:

git clone https://github.com/aws-samples/sample-SecurityHub-Automation-Rule-Migration.git

2. Run the scripts following the instructions of the README file, which will contain the most up-to-date implementation instructions. This will generate a CloudFormation template that will create the new Security Hub automation rules. Deploy the CloudFormation template using the AWS CLI or console. For more details, see the Create a stack from the CloudFormation console or the README file.

When deployment is complete, you can use the Security Hub console to review your migrated automation rules. Remember that rules are created in a DISABLED state by default. Review each rule’s criteria and actions carefully, checking that they match your intended automation workflow. You can also preview what existing findings would have matched each automation rule in the console.

To review and validate migrated rules:

1. Go to the Security Hub console and choose Automations from the navigation pane.

Figure 2: Security Hub Automations page

Figure 2: Security Hub Automations page

2. Select a rule and then choose Edit at the top of the page.

Figure 3: Security Hub automation rule details

Figure 3: Security Hub automation rule details

3. Choose Preview matching findings. It’s possible that no findings will be returned even if the automation rule is behaving as expected. This means only that there are currently no findings matching the rule criteria in Security Hub. In this case, you can still review the rule criteria.

Figure 4: Security Hub Edit automation rule page

Figure 4: Security Hub Edit automation rule page

4. After validating a rule’s configuration, you can enable it through the console from the rule editing page. You can also update the CloudFormation stack. If you didn’t need to change any criteria or actions of your automation rules, you can re-run the scripts with the optional —create-enabled flag to reproduce the CloudFormation template with all rules enabled and deploy it as an update to the existing stack.

Pay attention to any rules that have partially migrated actions, which will be noted in the Description of each rule. This means one or more actions from the original rule in Security Hub CSPM aren’t supported in Security Hub and the rule might behave differently than intended. The solution also produces a migration report that includes which rules were partially migrated and specifies which actions from the original rule could not be migrated. Review these rules carefully because they might behave differently than expected and need to be modified or recreated.

Figure 5: Review the descriptions of partially migrated automation rules

Figure 5: Review the descriptions of partially migrated automation rules

Conclusion

The new AWS Security Hub provides enhanced capabilities for aggregating, correlating, and contextualizing your security findings. While the schema change from ASFF to OCSF brings improved interoperability and integration options, it requires existing automation rules to be migrated. The solution provided in this post helps automate this migration process through discovering your existing rules, transforming them to the new schema, and generating CloudFormation templates that preserve rule order and Regional context.

After migrating your automation rules, start by reviewing the migration report to identify any rules that weren’t fully migrated. Pay special attention to rules marked as partially migrated, because these might behave differently than their original versions. We recommend testing each rule in a disabled state and validating that rules work together as expected—especially rules that operate on the same fields—before enabling them in your environment.

To learn more about Security Hub and its enhanced capabilities, see the Security Hub User Guide.
If you have feedback about this post, submit comments in the Comments section below.

Joe Wagner

Joe Wagner

Joe is a Senior Security Specialist Solutions Architect who focuses on AWS security services. He loves that cybersecurity is always changing and takes pride in helping his customers navigate it all. Outside of work, you’ll find him trying new hobbies, exploring local restaurants, and getting outside as much as he can.

Ahmed Adekunle

Ahmed Adekunle

Ahmed is a Security Specialist Solutions Architect focused on detection and response services at AWS. Before AWS, his background was in business process management and AWS tech consulting, helping customers use cloud technology to transform their business. Outside of work, Ahmed enjoys playing soccer, supporting less privileged activities, traveling, and eating spicy food, specifically African cuisine.

Salifu (Sal) Ceesay

Salifu (Sal) Ceesay

Sal is a Technical Account Manager at Amazon Web Services (AWS) specializing in financial services. He partners with organizations to operationalize and optimize managed solutions across many use cases, with expertise in native incident detection and response services. Beyond his professional pursuits, Sal enjoys gardening, playing and watching soccer, traveling, and participating in various outdoor activities with his family.

Critical vulnerabilities in Fortinet CVE-2025-59718, CVE-2025-59719 exploited in the wild

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/etr-critical-vulnerabilities-in-fortinet-cve-2025-59718-cve-2025-59719-exploited-in-the-wild

Overview

A recently disclosed pair of vulnerabilities affecting Fortinet devices—CVE-2025-59718 and CVE-2025-59719—are drawing urgent attention after confirmation of their active exploitation in the wild. The vulnerabilities carry a critical CVSSv3 score and allow an unauthenticated remote attacker to bypass authentication using a crafted SAML message, ultimately gaining administrative access to the device. Current information indicates that the two CVEs have the same root cause and are differentiated by the products affected: CVE-2025-59719 specifically affects FortiWeb, while CVE-2025-59718 affects FortiOS, FortiProxy, and FortiSwitchManager.

While the vulnerable FortiCloud SSO feature is disabled by default in factory settings, it is automatically enabled when a device is registered to FortiCare via the GUI, unless an administrator explicitly opts out. This behavior significantly increases the likelihood of exposure across registered deployments. Arctic Wolf has confirmed active exploitation and CVE-2025-59718 was added to CISA’s Known Exploited Vulnerabilities (KEV) catalog on December 16.

Observed attacks show threat actors authenticating as the admin user and immediately downloading the system configuration file, which often contains hashed credentials. As a result, any organization with indicators of compromise must assume credential exposure and respond accordingly. A vendor patch is available, and organizations can also take immediate defensive action by disabling FortiCloud SSO administrative login while remediation efforts are underway.

Rapid7 observations

As of December 17, 2025, Rapid7 has observed CVE-2025-59718 exploitation attempts being performed against honeypots. Furthermore, a proof-of-concept exploit that resembles the observed honeypot requests has been posted to GitHub. These exploits are in the process of being validated against confirmed vulnerable targets.

Mitigation guidance

On December 9th, 2025, Fortinet published an advisory that outlines remediation steps for CVE-2025-59718 and CVE-2025-59719. According to Fortinet, the following versions are affected, and the fixed versions for each main release branch are also listed.

Fortinet’s advisory states that CVE-2025-59718 affects the following products and versions:

  • FortiOS

    • 7.6 branch: versions 7.6.0 through 7.6.3 are affected, upgrade to 7.6.4 or above.

    • 7.4 branch: versions 7.4.0 through 7.4.8 are affected, upgrade to 7.4.9 or above.

    • 7.2 branch: versions 7.2.0 through 7.2.11 are affected, upgrade to 7.2.12 or above.

    • 7.0 branch: versions 7.0.0 through 7.0.17 are affected, upgrade to 7.0.18 or above.

  • FortiProxy

    • 7.6 branch: versions 7.6.0 through 7.6.3 are affected, upgrade to 7.6.4 or above.

    • 7.4 branch: versions 7.4.0 through 7.4.10 are affected, upgrade to 7.4.11 or above.

    • 7.2 branch: versions 7.2.0 through 7.2.14 are affected, upgrade to 7.2.15 or above.

    • 7.0 branch: versions 7.0.0 through 7.0.21 are affected, upgrade to 7.0.22 or above.

  • FortiSwitchManager

    • 7.2 branch: versions 7.2.0 through 7.2.6 are affected, upgrade to 7.2.7 or above.

    • 7.0 branch: versions 7.0.0 through 7.0.5 are affected, upgrade to 7.0.6 or above.

Fortinet’s advisory states that CVE-2025-59719 affects the following product and versions:

  • FortiWeb

    • 8.0 branch: version 8.0.0 is affected, upgrade to 8.0.1 or above.

    • 7.6 branch: versions 7.6.0 through 7.6.4 are affected, upgrade to 7.6.5 or above.

    • 7.4 branch: versions 7.4.0 through 7.4.9 are affected, upgrade to 7.4.10 or above.

For the latest mitigation guidance, please refer to the Fortinet security advisory.

Rapid7 customers

Exposure Command, InsightVM and Nexpose

Exposure Command, InsightVM, and Nexpose customers can assess their exposure to CVE-2025-59718 and CVE-2025-59719 with vulnerability checks expected to be available in the December 17 content release.

Updates

  • December 17, 2025: Initial publication

[$] Going boldly into the COSMIC desktop environment

Post Syndicated from jzb original https://lwn.net/Articles/1050268/

After three years of development, Linux hardware provider System76
has declared
the COSMIC desktop
environment
stable. It shipped COSMIC Epoch 1 as part of the
long-awaited Pop!_OS 24.04 LTS
release on December 11, just in time for Linux enthusiasts to
have something to tinker with over the end-of-year holidays. With the
stable release out the door, it seemed like a good time to check back
in on COSMIC and see how it has evolved since the first alpha. For a first
stable release of a new desktop environment, COSMIC shows a lot of
promise and room to grow.

Test for React2Shell with Application Security using New Functionality

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/pt-react2shell-testing-new-application-security-functionality-appsec-dast

Following disclosure of the React2Shell vulnerability (CVE-2025-55182), a maximum-severity Remote Code Execution (RCE) in React Server Components (RSC) a.k.a. the Flight protocol, security teams are assessing exposure and validating fixes. React and ecosystem vendors have released patches; exploitation in the wild has been reported, so rapid validation matters.

What is React2Shell? 

React2Shell is an unauthenticated RCE flaw caused by insecure Flight payload deserialization in server-side React/RSC implementations (including popular frameworks like Next.js). It carries a CVSS 10.0 rating and affects React versions 19.0.0, 19.1.0, 19.1.1, and 19.2.0 as well as Next.js versions 15.0.0-15.1.6 and 16.0.0-16.0.6 prior to recent patches. You can read more about it in this detailed CVE overview blog post.  

In this detailed writeup, we will share how our customers can specifically test for React2Shell with Rapid7’s Application Security solution.

Testing for React2Shell with application security

With our dynamic application security testing (DAST) solution, customers can assess the risk of their applications. Rapid7 allows you to configure various attacks of your applications to identify response behaviors that make your applications more vulnerable to attacks. These attacks are run during scans that you can customize based on your needs. In this case, we’ve extended our RCE attack module to include a check for React2Shell.

What does this mean? Customers can now run an Attack Injection using the RCE, which includes an attack type for React2Shell. Our React2Shell vulnerability detection will simulate an attacker on your website. This is a benign attack which will not execute any code and only shows that RCE is possible. Rapid7 will validate the exploitability of the application and the associated risk. 

How to run a React2Shell attack in the Rapid7 DAST

You can scan for this new RCE attack using either the new Arbitrary Code Execution attack template we have created or by creating your own custom attack template and selecting the RCE module. We have added some steps for you to follow below:

Default attack template option:

Choose the Arbitrary Code Execution attack template in your scan configuration: 

⠀

Arbitrary-code-execution-attack-template.png
Default Arbitrary Code Execution attack template with RCE attack module

Custom attack template option:

custom-Attack-Template-RCE-module.png
Custom Attack Template with RCE module

Run a scan

Choosing the scan configuration you made earlier, scan against your selected app(s).

Scan results – React2Shell RCE finding

Now that you have run your scan, you can review the results to see if your app(s) have any findings. These will include remediation advice that you can follow.

⠀

3-Scan-results-React2Shell-RCE-finding.png

Manage attack templates

You can now manage your attack templates by navigating to the appropriate section and selecting the Arbitrary Code Execution attack template as below. 

⠀

manage-attack-templates-rapid7.png
Manage attack templates

What’s next?

Patch immediately, upgrade React to 19.0.1, 19.1.2, or 19.2.1 (or newer). For Next.js, the recommended action is to update to the following respective patched versions: 15.2.6, 15.3.6, 15.4.8, 15.5.7, 16.0.7, or later*. You should seek to remediate this vulnerability on an urgent basis, outside of normal patch cycles and consider temporary web application firewall (WAF) rules for Flight endpoints while patching. If you’re looking to validate any fixes you have implemented, feel free to run a validation scan with our application security tool to verify the fixes are correct.

* For Next.js, the recommendation from Nextjs is to update to the following respective patched versions: 15.0.5, 15.1.9, 15.2.6, 15.3.6, 15.4.8, 15.5.7, 16.0.7, or later. However, we have identified that versions 15.0.5 and 15.1.9 have a different critical vulnerability and would recommend against using them.

The collective thoughts of the interwebz