Tag Archives: Amazon Elastic Block Store (Amazon EBS)

New – Create application-consistent snapshots using Amazon Data Lifecycle Manager and custom scripts

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-create-application-consistent-snapshots-using-amazon-data-lifecycle-manager-and-custom-scripts/

Amazon Data Lifecycle Manager now supports the use of pre-snapshot and post-snapshot scripts embedded in AWS Systems Manager documents. You can use these scripts to ensure that Amazon Elastic Block Store (Amazon EBS) snapshots created by Data Lifecycle Manager are application-consistent. Scripts can pause and resume I/O operations, flush buffered data to EBS volumes, and so forth. As part of this launch we are also publishing a set of detailed blog posts that show you how to use this feature with self-managed relational databases and Windows Volume Shadow Copy Service (VSS).

Data Lifecycle Manager (DLM) Recap
As a quick recap, Data Lifecycle Manager helps you to automate the creation, retention, and deletion of Amazon EBS volume snapshots. Once you have completed the prerequisite steps such as onboarding your EC2 instance to AWS Systems Manager, setting up an IAM role for DLM, and tagging your SSM documents, you simply create a lifecycle policy and indicate (via tags) the applicable Amazon Elastic Compute Cloud (Amazon EC2) instances, set a retention model, and let DLM do the rest. The policies specify when they are to be run, what is to be backed up, and how long the snapshots must be retained. For a full walk-through of DLM, read my 2018 blog post, New – Lifecycle Management for Amazon EBS Snapshots.

Application Consistent Snapshots
EBS snapshots are crash-consistent, meaning that they represent the state of the associated EBS volume at the time that the snapshot was created. This is sufficient for many types of applications, including those that do not use snapshots to capture the state of an active relational database. To make a snapshot that is application-consistent, it is necessary to take pending transactions into account (either waiting for them to finish or causing them to fail), momentarily pause further write operations, take the snapshot, and then resume normal operations.

And that’s where today’s launch comes in. DLM now has the ability to tell the instance to prepare for an application-consistent backup. The pre-snapshot script can manage pending transactions, flush in-memory data to persistent storage, freeze the filesystem, or even bring the application or database to a stop. Then the post-snapshot script can bring the application or database back to life, reload in-memory caches from persistent storage, thaw the filesystem, and so forth.

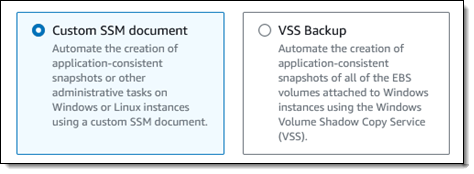
In addition to the base-level support for custom scripts, you can also use this feature to automate the creation of VSS Backup snapshots:

Pre and Post Scripts
The new scripts apply to DLM policies for instances. Let’s assume that I have created a policy that references SSM documents with pre-snapshot and post-snapshot scripts, and that it applies to a single instance. Here’s what happens when the policy is run per its schedule:

  1. The pre-snapshot script is started from the SSM document.
  2. Each command in the script is run and the script-level status (success or failure) is captured. If enabled in the policy, DLM will retry failed scripts.
  3. Multi-volume EBS snapshots are initiated for EBS volumes attached to the instance, with further control via the policy.
  4. The post-snapshot script is started from the SSM document,
  5. Each command in the script is run and and the script-level status (success or failure) is captured.

The policy contains options that give you control over the actions that are taken (retry, continue, or skip) when either of the scripts times out or fails. The status is logged, Amazon CloudWatch metrics are published, Amazon EventBridge events are emitted, and the status is also encoded in tags that are automatically assigned to each snapshot.

The pre-snapshot and post-snapshot scripts can perform any of the actions that are allowed in a command document: running shell scripts, running PowerShell scripts, and so forth. The actions must complete within the timeout specified in the policy, with an allowable range of 10 seconds to 120 seconds.

Getting Started
You will need to have a detailed understanding of your application or database in order to build a robust pair of scripts. In addition to handling the “happy path” when all goes well, your scripts need to plan for several failure scenarios. For example, a pre-snapshot script should fork a background task that will serve as a failsafe in case the post-snapshot script does not work as expected. Each script must return a shell-level status code, as detailed here.

Once I have written and tested my scripts and packaged them as SSM documents, I open the Data Lifecycle Manager page in the EC2 Console, select EBS snapshot policy, and click Next step:

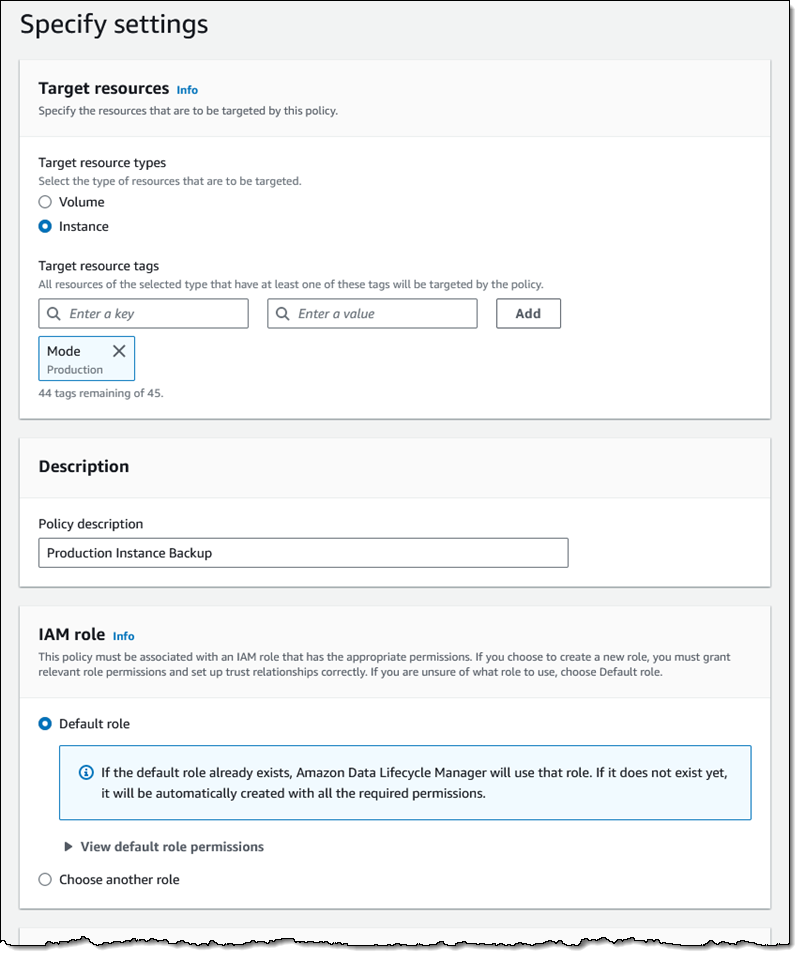
I target all of my instances that are tagged with a Mode of Production, and use the default IAM role (if you use a different role, it must enable access to SSM), leave the rest of the values as-is, and proceed:

On the next page I scroll down to Pre and post scripts and expand the section. I click Enable pre and post scripts, choose Custom SSM document, and then select my SSM document from the menu. I also set the timeout and retry options, and choose to default to a crash-consistent backup if one of my scripts fails. I click Review policy, do one final check, and click Create policy on the following page:

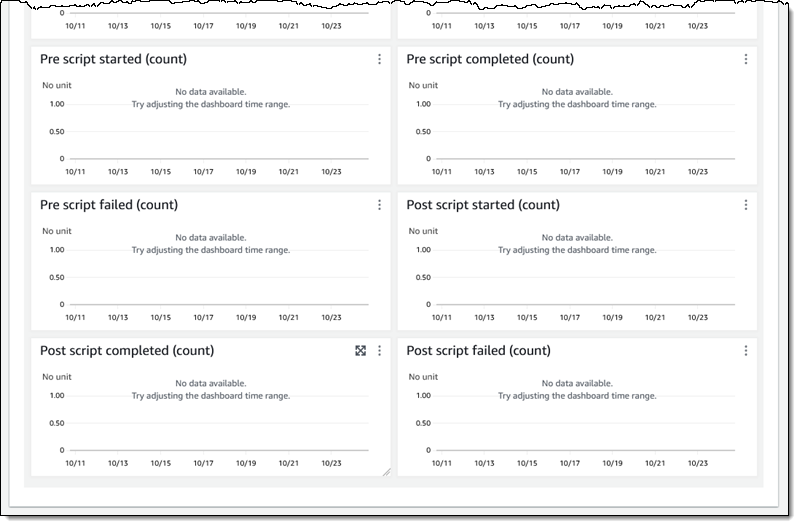
My policy is created, and will take effect right away. After it has run at least once, I can inspect the CloudWatch metrics to check for starts, completions, and failures:

Additional Reading
Here are the first of the detailed blog posts that I promised you earlier:

We have more in the works for later this year and I will update the list above when they are published.

You can also read the documentation to learn more.

DLM Videos
While I’ve got your attention, I would like to share a couple of helpful videos with you:

This new feature is available now and you can start using it today!

Jeff;

Quickly Restore Amazon EC2 Mac Instances using Replace Root Volume capability

Post Syndicated from Macey Neff original https://aws.amazon.com/blogs/compute/new-reset-amazon-ec2-mac-instances-to-a-known-state-using-replace-root-volume-capability/

This post is written by Sebastien Stormacq, Principal Developer Advocate.

Amazon Elastic Compute Cloud (Amazon EC2) now supports replacing the root volume on a running EC2 Mac instance, enabling you to restore the root volume of an EC2 Mac instance to its initial launch state, to a specific snapshot, or to a new Amazon Machine Image (AMI).

Since 2021, we have offered on-demand and pay-as-you-go access to Amazon EC2 Mac instances, in the same manner as our Intel, AMD and Graviton-based instances. Amazon EC2 Mac instances integrate all the capabilities you know and love from macOS with dozens of AWS services such as Amazon Virtual Private Cloud (VPC) for network security, Amazon Elastic Block Store (EBS) for expandable storage, Elastic Load Balancing (ELB) for distributing build queues, Amazon FSx for scalable file storage, and AWS Systems Manager Agent (SSM Agent) for configuring, managing, and patching macOS environments.

Just like for every EC2 instance type, AWS is responsible for protecting the infrastructure that runs all of the services offered in the AWS cloud. To ensure that EC2 Mac instances provide the same security and data privacy as other Nitro-based EC2 instances, Amazon EC2 performs a scrubbing workflow on the underlying Dedicated Host as soon as you stop or terminate an instance. This scrubbing process erases the internal SSD, clears the persistent NVRAM variables, and updates the device firmware to the latest version enabling you to run the latest macOS AMIs. The documentation has more details about this process.

The scrubbing process ensures a sanitized dedicated host for each EC2 Mac instance launch and takes some time to complete. Our customers have shared two use cases where they may need to set back their instance to a previous state in a shorter time period or without the need to initiate the scrubbing workflow. The first use case is when patching an existing disk image to bring OS-level or applications-level updates to your fleet, without manually patching individual instances in-place. The second use case is during continuous integration and continuous deployment (CI/CD) when you need to restore an Amazon EC2 Mac instance to a defined well-known state at the end of a build.

To restart your EC2 Mac instance in its initial state without stopping or terminating them, we created the ability to replace the root volume of an Amazon EC2 Mac instance with another EBS volume. This new EBS volume is created either from a new AMI, an Amazon EBS Snapshot, or from the initial volume state during boot.

You just swap the root volume with a new one and initiate a reboot at OS-level. Local data, additional attached EBS volumes, networking configurations, and IAM profiles are all preserved. Additional EBS volumes attached to the instance are also preserved, as well as the instance IP addresses, IAM policies, and security groups.

Let’s see how Replace Root Volume works

To prepare and initiate an Amazon EBS root volume replacement, you can use the AWS Management Console, the AWS Command Line Interface (AWS CLI), or one of our AWS SDKs. For this demo, I used the AWS CLI to show how you can automate the entire process.

To start the demo, I first allocate a Dedicated Host and then start an EC2 Mac instance, SSH-connect to it, and install the latest version of Xcode. I use the open-source xcodeinstall CLI tool to download and install Xcode. Typically, you also download, install, and configure a build agent and additional build tools or libraries as required by your build pipelines.

Once the instance is ready, I create an Amazon Machine Image (AMI). AMIs are disk images you can reuse to launch additional and identical EC2 Mac instances. This can be done from any machine that has the credentials to make API calls on your AWS account. In the following, you can see the commands I issued from my laptop’s Terminal application.

#
# Find the instance’s ID based on the instance name tag
#
~ aws ec2 describe-instances \
--filters "Name=tag:Name,Values=RRV-Demo" \
--query "Reservations[].Instances[].InstanceId" \
--output text 

i-0fb8ffd5dbfdd5384

#
# Create an AMI based on this instance
#
~ aws ec2 create-image \
--instance-id i-0fb8ffd5dbfdd5384 \
--name "macOS_13.3_Gold_AMI"	\
--description "macOS 13.2 with Xcode 13.4.1"

{
 
"ImageId": "ami-0012e59ed047168e4"
}

It takes a few minutes to complete the AMI creation process.

After I created this AMI, I can use my instance as usual. I can use it to build, test, and distribute my application, or make any other changes on the root volume.

When I want to reset the instance to the state of my AMI, I initiate the replace root volume operation:

~ aws ec2 create-replace-root-volume-task	\
--instance-id i-0fb8ffd5dbfdd5384 \
--image-id ami-0012e59ed047168e4
{
"ReplaceRootVolumeTask": {
"ReplaceRootVolumeTaskId": "replacevol-07634c2a6cf2a1c61", "InstanceId": "i-0fb8ffd5dbfdd5384",
"TaskState": "pending", "StartTime": "2023-05-26T12:44:35Z", "Tags": [],
"ImageId": "ami-0012e59ed047168e4", "SnapshotId": "snap-02be6b9c02d654c83", "DeleteReplacedRootVolume": false
}
}

The root Amazon EBS volume is replaced with a fresh one created from the AMI, and the system triggers an OS-level reboot.

I can observe the progress with the DescribeReplaceRootVolumeTasks API

~ aws ec2 describe-replace-root-volume-tasks \
--replace-root-volume-task-ids replacevol-07634c2a6cf2a1c61

{
"ReplaceRootVolumeTasks": [
{
"ReplaceRootVolumeTaskId": "replacevol-07634c2a6cf2a1c61", "InstanceId": "i-0fb8ffd5dbfdd5384",
"TaskState": "succeeded", "StartTime": "2023-05-26T12:44:35Z",
"CompleteTime": "2023-05-26T12:44:43Z", "Tags": [],
"ImageId": "ami-0012e59ed047168e4", "DeleteReplacedRootVolume": false
}
]
}

After a short time, the instance becomes available again, and I can connect over ssh.

~ ssh [email protected]
Warning: Permanently added '3.0.0.86' (ED25519) to the list of known hosts.
Last login: Wed May 24 18:13:42 2023 from 81.0.0.0

┌───┬──┐	 |  |_ )
│ ╷╭╯╷ │	_| (	/
│ └╮	│   |\  |  |
│ ╰─┼╯ │ Amazon EC2
└───┴──┘ macOS Ventura 13.2.1
 
ec2-user@ip-172-31-58-100 ~ %

Additional thoughts

There are a couple of additional points to know before using this new capability:

  • By default, the old root volume is preserved. You can pass the –-delete-replaced-root-volume option to delete it automatically. Do not forget to delete old volumes and their corresponding Amazon EBS Snapshots when you don’t need them anymore to avoid being charged for them.
  • During the replacement, the instance will be unable to respond to health checks and hence might be marked as unhealthy if placed inside an Auto Scaled Group. You can write a custom health check to change that behavior.
  • When replacing the root volume with an AMI, the AMI must have the same product code, billing information, architecture type, and virtualization type as that of the instance.
  • When replacing the root volume with a snapshot, you must use snapshots from the same lineage as the instance’s current root volume.
  • The size of the new volume is the largest of the AMI’s block device mapping and the size of the old Amazon EBS root volume.
  • Any non-root Amazon EBS volume stays attached to the instance.
  • Finally, the content of the instance store (the internal SSD drive) is untouched, and all other meta-data of the instance are unmodified (the IP addresses, ENI, IAM policies etc.).

Pricing and availability

Replace Root Volume for EC2 Mac is available in all AWS Regions where Amazon EC2 Mac instances are available. There is no additional cost to use this capability. You are charged for the storage consumed by the Amazon EBS Snapshots and AMIs.

Check other options available on the API or AWS CLI and go configure your first root volume replacement task today!

New – NVMe Reservations for Amazon Elastic Block Store io2 Volumes

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/new-nvme-reservations-for-amazon-elastic-block-store-io2-volumes/

Amazon Elastic Block Store (Amazon EBS) io2 and io2 Block Express volumes now support storage fencing using NVMe reservations. As I learned while writing this post, storage fencing is used to regulate access to storage for a compute or database cluster, ensuring that just one host in the cluster has permission to write to the volume at any given time. For example, you can set up SQL Server Failover Cluster Instances (FCI) and get higher application availability within a single Availability Zone without the need for database replication.

As a quick refresher, io2 Block Express volumes are designed to meet the needs of the most demanding I/O-intensive applications running on Nitro-based Amazon Elastic Compute Cloud (Amazon EC2) instances. Volumes can be as big as 64 TiB, and deliver SAN-like performance with up to 256,000 IOPS/volume and 4,000 MB/second of throughput, all with 99.999% durability and sub-millisecond latency. The volumes support other advanced EBS features including encryption and Multi-Attach, and can be reprovisioned online without downtime. To learn more, you can read Amazon EBS io2 Block Express Volumes with Amazon EC2 R5b Instances Are Now Generally Available.

Using Reservations
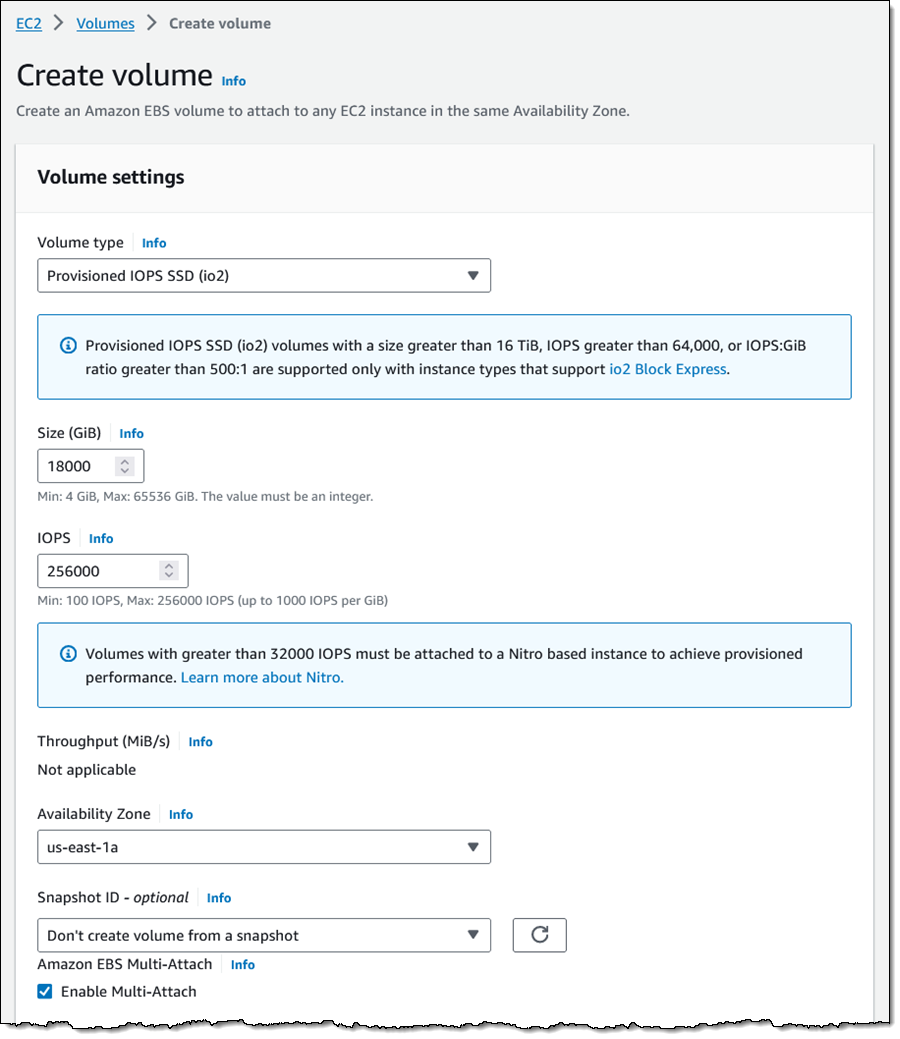
To make use of reservations, you simply create an io2 volume with Multi-Attach enabled, and then attach it to one or more Nitro-based EC2 instances (see Provisioned IOPS Volumes for a full list of supported instance types):

If you have existing io2 Block Express volumes, you can enable reservations by detaching the volumes from all of the EC2 instances, and then reattaching them. Reservations will be enabled as soon as you make the first attachment. If you are running Windows Server using AMIs data-stamped 2023.08 or earlier you will need to install the aws_multi_attach driver as described in AWS NVMe Drivers for Windows Instances.

Things to Know
Here are a couple of things to keep in mind regarding NVMe reservations:

Operating System Support – You can use NVMe reservations with Windows Server (2012 R2 and above, 2016, 2019, and 2022), SUSE SLES 12 SP3 and above, RHEL 8.3 and above, and Amazon Linux 2 & later (read NVMe reservations to learn more).

Cluster and Volume Managers – Windows Server Failover Clustering is supported; we are currently working to qualify other cluster and volume managers.

Charges – There are no additional charges for this feature. Each reservation counts as an I/O operation.

Jeff;

AWS Weekly Roundup: Farewell EC2-Classic, EBS at 15 Years, and More (Sept. 4, 2023)

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-farewell-ec2-classic-ebs-at-15-years-and-more-sept-4-2023/

Last week, there was some great reading about Amazon Elastic Compute Cloud (Amazon EC2) and Amazon Elastic Block Store (Amazon EBS) written by AWS tech leaders.

Dr. Werner Vogels wrote Farewell EC2-Classic, it’s been swell, celebrating the 17 years of loyal duty of the original version that started what we now know as cloud computing. You can read how it made the process of acquiring compute resources simple, even though the stack running behind the scenes was incredibly complex.

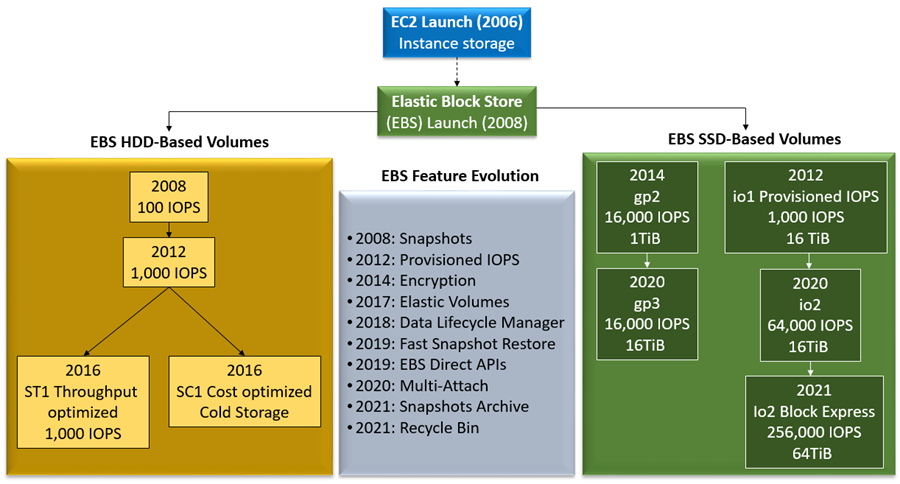
We have come a long way since 2006, and we’re not done innovating for our customers. As celebrated in this year’s AWS Storage Day, Amazon EBS was launched 15 years ago this month. James Hamilton, SVP and distinguished engineer at Amazon, wrote Amazon EBS at 15 Years, about how the service has evolved to handle over 100 trillion I/O operations a day, and transfers over 13 exabytes of data daily.

As Dr. Werner said in his piece, “it’s a reminder that building evolvable systems is a strategy, and revisiting your architectures with an open mind is a must.” Our innovation efforts driven by customer feedback continue today, and this week is no different.

Last Week’s Launches
Here are some launches that got my attention:

Renaming Amazon Kinesis Data Analytics to Amazon Managed Service for Apache Flink – You can now use Amazon Managed Service for Apache Flink, a fully managed and serverless service for you to build and run real-time streaming applications using Apache Flink. All your existing running applications in Kinesis Data Analytics will work as-is, without any changes. To learn more, see my blog post.

Extended Support for Amazon Aurora and Amazon RDS – You can now get more time for support, up to three years, for Amazon Aurora and Amazon RDS database instances running MySQL 5.7, PostgreSQL 11, and higher major versions. This e will allow you time to upgrade to a new major version to help you meet your business requirements even after the community ends support for these versions.

Enhanced Starter Template for AWS Step Functions Workflow Studio – You can now use starter templates to streamline the process of creating and prototyping workflows swiftly, plus a new code mode, which enables builders to move easily between design and code authoring views. With the improved authoring experience in Workflow Studio, you can seamlessly alternate between a drag-and-drop visual builder experience or the new code editor so that you can pick your preferred tool to accelerate development.

To learn more, see Enhancing Workflow Studio with new features for streamlined authoring in the AWS Compute Blog.

Email Delivery History for Every Email in Amazon SES – You can now troubleshoot individual email delivery problems, confirm delivery of critical messages, and identify engaged recipients on a granular, single email basis. Email senders can investigate trends in delivery performance and see delivery and engagement status for each email sent using Amazon SES Virtual Deliverability Manager.

Response Streaming through Amazon SageMaker Real-time Inference – You can now continuously stream inference responses back to the client to help you build interactive experiences for various generative AI applications such as chatbots, virtual assistants, and music generators.

For more details on how to use response streaming along with examples, see Invoke to Stream an Inference Response and How containers should respond in the AWS documentation, and Elevating the generative AI experience: Introducing streaming support in Amazon SageMaker hosting in the AWS Machine Learning Blog.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
Some other updates and news that you might have missed:

AI & Sports: How AWS & the NFL are Changing the Game – Over the last 5 years, AWS has partnered with the National Football League (NFL), helping fans better understand the game, helping broadcasters tell better stories, and helping teams use data to improve operations and player safety. Watch AWS CEO, Adam Selipsky, former NFL All-Pro Larry Fitzgerald, and the NFL Network’s Cynthia Frelund during their earlier livestream discussing the intersection of artificial intelligence and machine learning in sports.

Amazon Bedrock Story from Amazon Science – This is a good article explaining the benefits of using Amazon Bedrock to build and scale generative AI applications with leading foundation models, including Amazon’s Titan FMs, which focus on responsible AI to avoid toxic content.

Amazon EC2 Flexibility Score – This is an open source tool developed by AWS to assess any configuration used to launch instances through an Auto Scaling Group (ASG) against the recommended EC2 best practices. It converts the best practice adoption into a “flexibility score” that can be used to identify, improve, and monitor the configurations.

To learn more open-source news and updates, see this newsletter curated by my colleague Ricardo to bring you the latest open source projects, posts, events, and more.

Upcoming AWS Events
Check your calendars and sign up for these AWS events:

AWS re:InventAWS re:Invent 2023Ready to start planning your re:Invent? Browse the session catalog now. Join us to hear the latest from AWS, learn from experts, and connect with the global cloud community.

AWS Global SummitsAWS Summits – The last in-person AWS Summit will be held in Johannesburg on Sept. 26.

AWS Community Days AWS Community Day– Join a community-led conference run by AWS user group leaders in your region: Aotearoa (Sept. 6), Lebanon (Sept. 9), Munich (Sept. 14), Argentina (Sept. 16), Spain (Sept. 23), and Chile (Sept. 30). Visit the landing page to check out all the upcoming AWS Community Days.

CDK Day – A community-led fully virtual event on Sept. 29 with tracks in English and Spanish about CDK and related projects. Learn more at the website.

You can browse all upcoming AWS-led in-person and virtual events, and developer-focused events such as AWS DevDay.

Channy

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Welcome to AWS Storage Day 2023

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/welcome-to-aws-storage-day-2023/

Welcome to the fifth annual AWS Storage Day! This virtual event is happening today starting at 9:00 AM Pacific Time (12:00 PM Eastern Time) and is available for you to watch on the AWS On Air Twitch channel. The first AWS Storage Day was hosted in 2019, and this event has grown into an innovation day that we look forward to delivering to you every year. In last year’s Storage Day post, I wrote about the constant innovations in AWS Storage aimed at helping you put your data to work while keeping it secure and protected. This year, Storage Day is focused on storage for AI/ML, data protection and resiliency, and the benefits of moving to the cloud.

AWS Storage Day Key Themes
When it comes to storage for AI/ML, data volumes are increasing at an unprecedented rate, exploding from terabytes to petabytes and even to exabytes. With a modern data architecture on AWS, you can rapidly build scalable data lakes, use a broad and deep collection of purpose-built data services, scale your systems at a low cost without compromising performance, share data across organizational boundaries, and manage compliance, security, and governance, allowing you to make decisions with speed and agility at scale.
To train machine learning models and build Generative AI applications, you must have the right data strategy in place. So, I’m happy to see that, among the list of sessions to look forward to at the live event, the Optimize generative AI and ML with AWS Infrastructure session will discuss how you can transform your data into meaningful insights.

Whether you’re just getting started with the cloud, planning to migrate applications to AWS, or already building applications on AWS, we have resources to help you protect your data and meet your business continuity objectives. Our data protection and resiliency features and solutions can help you meet your business continuity goals and deliver disaster recovery during data loss events, across recovery point and time objectives (RPO and RTO). With the unprecedented data growth happening in the world today, determining where your data is stored, how it’s secured, and who has access to it is a higher priority than ever. Be sure to join the Protect data in AWS amid a rapidly evolving cyber landscape session to learn more.

When moving data to the cloud, you need to understand where you’re moving it for different use cases, the types of data you’re moving, and the network resources available, among other considerations. There are many reasons to move to the cloud, recently, Enterprise Strategy Group (ESG) validated that organizations reduced compute, networking, and storage costs by up to 66 percent by migrating on-premises workloads to AWS Cloud infrastructure. ESG confirmed that migrating on-premises workloads to AWS provides organizations with reduced costs, increased performance, improved operational efficiency, faster time to value, and improved business agility.
We have a number of sessions that discuss how to move to the cloud, based on your use case. I’m most looking forward to the Hybrid cloud storage and edge compute: AWS, where you need it session, which will discuss considerations for workloads that can’t fully move to the cloud.

Tune in to learn from experts about new announcements, leadership insights, and educational content related to the broad portfolio of AWS Storage services and features that address all these themes and more. Today, we have announcements related to Amazon Simple Storage Service (Amazon S3), Amazon FSx for Windows File Server, Amazon Elastic File System (Amazon EFS), Amazon FSx for OpenZFS, and more.

Let’s get into it.

15 Years of Amazon EBS
Not long ago, I was reading Jeff Barr’s post titled 15 Years of AWS Blogging! In this post, Jeff mentioned a few posts he wrote for the earliest AWS services and features. Amazon Elastic Block Store (Amazon EBS) is on this list as a service that simplifies the use of Amazon EC2.

Well, it’s been 15 years since the launch of Amazon EBS was announced, and today we celebrate 15 years of this service. If you were one of the original users who put Amazon EBS to good use and provided us with the very helpful feedback that helped us invent and simplify, iterate and improve, I’m sure you can’t believe how time flies. Today, Amazon EBS handles more than 100 trillion I/O operations daily, and over 390 million EBS volumes are created every day.

If you’re new to Amazon EBS, join us for a fireside chat with Matt Garman, Senior Vice President, Sales, Marketing, and Global Services at AWS, and learn the strategy and customer challenges behind the launch of the service in 2008. You’ll also hear from long-term EBS customer, Stripe, about its growth with EBS since Stripe was launched 12 years ago.

Amazon EBS has continuously improved its scalability and performance to support more customer workloads as the direct storage attachment for Amazon EC2 instances. With the launch of Amazon EC2 M7i instances, powered by custom 4th Generation Intel Xeon Scalable processors, on August 2, you can attach up to 128 Amazon EBS volumes, an increase from 28 on a previous generation M6i instance. The higher number of volume attachments means you can increase storage density per instance and improve resource utilization, reducing total compute cost.

You can host up to 127 containers per instance for larger database applications and scale them more cost effectively before needing to provision more instances and only pay for resources you need. With a higher number of volume attachments, you can fully utilize the memory and vCPU available on these powerful M7i instances as your database storage footprint grows. EBS is also increasing the number of multi-volume snapshots you can create, for up to 128 EBS volumes attached to an instance, enabling you to create crash-consistent backups of all volumes attached to an instance.

Join the 15 years of innovations with Amazon EBS session for a discussion about how the original vision for Amazon EBS has evolved to meet your growing demands for cloud infrastructure.

Mountpoint for Amazon S3
Now generally available, Mountpoint for Amazon S3 is a new open source file client that delivers high throughput access, lowering compute costs for data lakes on Amazon S3. Mountpoint for Amazon S3 is a file client that translates local file system API calls to S3 object API calls. Using Mountpoint for Amazon S3, you can mount an Amazon S3 bucket as a local file system on your compute instance, to access your objects through a file interface with the elastic storage and throughput of Amazon S3. Mountpoint for Amazon S3 supports sequential and random read operations on existing files, and sequential write operations for creating new files.

The Deep dive and demo of Mountpoint for Amazon S3 session demonstrates how to use the file client to access objects in Amazon S3 using file APIs, making it easier to store data at scale and maximize the value of your data with analytics and machine learning workloads. Read this blog post to learn more about Mountpoint for Amazon S3 and how to get started, including a demo.

Put Cold Storage to Work Faster with Amazon S3 Glacier Flexible Retrieval
Amazon S3 Glacier Flexible Retrieval improves data restore time by up to 85 percent, at no additional cost. Faster data restores automatically apply to the Standard retrieval tier when using Amazon S3 Batch Operations. These restores begin to return objects within minutes, so you can process restored data faster. Processing restored data in parallel with ongoing restores helps you accelerate data workflows and quickly respond to business needs. Now, whether you’re transcoding media, restoring operational backups, training machine learning models, or analyzing historical data, you can speed up your data restores from archive.

Coupled with the S3 Glacier improvements to restore throughput by up to 10 times for millions of objects announced in 2022, S3 Glacier data restores of all sizes now benefit from both faster starts and shorter completion times.

Join the Maximize the value of cold data with Amazon S3 Glacier session to learn how Amazon S3 Glacier is helping organizations of all sizes and from all industries transform their data archiving to unlock business value, increase agility, and save on storage costs. Read this blog post to learn more about the Amazon S3 Glacier Flexible Retrieval performance improvements and follow step-by-step guidance on how to get started with faster standard retrievals from S3 Glacier Flexible Retrieval.

Supporting a Broad Spectrum of File Workloads
To serve a broad spectrum of use cases that rely on file systems, we offer a portfolio of file system services, each targeting a different set of needs. Amazon EFS is a serverless file system built to deliver an elastic experience for sharing data across compute resources. Amazon FSx makes it easier and cost-effective for you to launch, run, and scale feature-rich, high-performance file systems in the cloud, enabling you to move to the cloud with no changes to your code, processes, or how you manage your data.

Power ML research and big data analytics with Amazon EFS
Amazon EFS offers serverless and fully scalable file storage, designed for high scalability in both storage capacity and throughput performance. Just last week, we announced enhanced support for faster read and write IOPS, making it easier to power more demanding workloads. We’ve improved the performance capabilities of Amazon EFS by adding support for up to 55,000 read IOPS and up to 25,000 write IOPS per file system. These performance enhancements help you to run more demanding workflows, such as machine learning (ML) research with KubeFlow, financial simulations with IBM Symphony, and big data processing with Domino Data Lab, Hadoop, and Spark.

Join the Build and run analytics and SaaS applications at scale session to hear how recent Amazon EFS performance improvements can help power more workloads.

Multi-AZ file systems on Amazon FSx for OpenZFS
You can now use a multi-AZ deployment option when creating file systems on Amazon FSx for OpenZFS, making it easier to deploy file storage that spans multiple AWS Availability Zones to provide multi-AZ resilience for business-critical workloads. With this launch, you can take advantage of the power, agility, and simplicity of Amazon FSx for OpenZFS for a broader set of workloads, including business-critical workloads like database, line-of-business, and web-serving applications that require highly available shared storage that spans multiple AZs.

The new multi-AZ file systems are designed to deliver high levels of performance to serve a broad variety of workloads, including performance-intensive workloads such as financial services analytics, media and entertainment workflows, semiconductor chip design, and game development and streaming, up to 21 GB per second of throughput and over 1 million IOPS for frequently accessed cached data, and up to 10 GB per second and 350,000 IOPS for data accessed from persistent disk storage.

Join the Migrate NAS to AWS to reduce TCO and gain agility session to learn more about multi-AZs with Amazon FSx for OpenZFS.

New, Higher Throughput Capacity Levels on Amazon FSx for Windows File Server
Performance improvements for Amazon FSx for Windows File Server help you accelerate time-to-results for performance-intensive workloads such as SQL Server databases, media processing, cloud video editing, and virtual desktop infrastructure (VDI).

We’re adding four new, higher throughput capacity levels to increase the maximum I/O available up to 12 GB per second from the previous I/O of 2 GB per second. These throughput improvements come with correspondingly higher levels of disk IOPS, designed to deliver an increase up to 350,000 IOPS.

In addition, by using FSx for Windows File Server, you can provision IOPS higher than the default 3 IOPS per GiB for your SSD file system. This allows you to scale SSD IOPS independently from storage capacity, allowing you to optimize costs for performance-sensitive workloads.

Join the Migrate NAS to AWS to reduce TCO and gain agility session to learn more about the performance improvements for Amazon FSx for Windows File Server.

Logically Air-Gapped Vault for AWS Backup
AWS Backup is a fully managed, policy-based data protection solution that enables customers to centralize and automate backup restores across 19 AWS services (spanning compute, storage, and databases) and third-party applications such as VMware Cloud on AWS and on-premises, as well as SAP HANA on Amazon EC2.

Today, we’re announcing the preview of logically air-gapped vault as a new type of AWS Backup Vault that acts as an additional layer of protection to mitigate against malware events. With logically air-gapped vault, customers can recover their application data through a different trusted account.

Join the Deep dive on data recovery for ransomware events session to learn more about logically air-gapped vault for AWS Backup.

Copy Data to and from Other Clouds with AWS DataSync
AWS DataSync is an online data movement and discovery service that simplifies data migration and helps you quickly, easily, and securely transfer your file or object data to, from, and between AWS storage services. In addition to support of data migration to and from AWS storage services, DataSync supports copying to and from other clouds such as Google Cloud Storage, Azure Files, and Azure Blob Storage. Using DataSync, you can move your object data at scale between Amazon S3 compatible storage on other clouds and AWS storage services such as Amazon S3. We’re now expanding the support of DataSync for copying data to and from other clouds to include DigitalOcean Spaces, Wasabi Cloud Storage, Backblaze B2 Cloud Storage, Cloudflare R2 Storage, and Oracle Cloud Storage.

Join the Identify and accelerate data migrations at scale session to learn more about this expanded support for DataSync.

Join Us Online
Join us today for the AWS Storage Day virtual event on the AWS On Air channel on Twitch. The event will be live starting at 9:00 AM Pacific Time (12:00 PM Eastern Time) on August 9. All sessions will be available on demand approximately two days after Storage Day.

We look forward to seeing you on Twitch!

– Veliswa 
AWS Cloud service considerations for designing multi-tenant SaaS solutions

Post Syndicated from Dennis Greene original https://aws.amazon.com/blogs/architecture/aws-cloud-service-considerations-for-designing-multi-tenant-saas-solutions/

An increasing number of software as a service (SaaS) providers are considering the move from single to multi-tenant to utilize resources more efficiently and reduce operational costs. This blog aims to inform customers of considerations when evaluating a transformation to multi-tenancy in the Amazon Web Services (AWS) Cloud. You’ll find valuable information on how to optimize your cloud-based SaaS design to reduce operating expenses, increase resiliency, and offer a high-performing experience for your customers.

Single versus multi-tenancy

In a multi-tenant architecture, resources like compute, storage, and databases can be shared among independent tenants. In contrast, a single-tenant architecture allocates exclusive resources to each tenant.

Let’s consider a SaaS product that needs to support many customers, each with their own independent deployed website. Using a single-tenant model (see Figure 1), the SaaS provider may opt to utilize a dedicated AWS account to host each tenant’s workloads. To contain their respective workloads, each tenant would have their own Amazon Elastic Compute Cloud (Amazon EC2) instances organized within an Auto Scaling group. Access to the applications running in these EC2 instances would be done via an Application Load Balancer (ALB). Each tenant would be allocated their own database environment using Amazon Relational Database Service (RDS). The website’s storage (consisting of PHP, JavaScript, CSS, and HTML files) would be provided by Amazon Elastic Block Store (EBS) volumes attached to the EC2 instances. The SaaS provider would have a control plane AWS account used to create and modify these tenant-specific accounts.

Single-tenant configuration

Figure 1. Single-tenant configuration

To transition to a multi-tenant pattern, the SaaS provider can use containerization to package each website, and a container orchestrator to deploy the websites across shared compute nodes (EC2 instances). Kubernetes can be employed as a container orchestrator, and a website would then be represented by a Kubernetes deployment and its associated pods. A Kubernetes namespace would serve as the logical encapsulation of the tenant-specific resources, as each tenant would be mapped to one Kubernetes namespace. The Kubernetes HorizontalPodAutoscaler can be utilized for autoscaling purposes, dynamically adjusting the number of replicas in the deployment on a given namespace based on workload demands.

When additional compute resources are required, tools such as the Cluster Autoscaler, or Karpenter, can dynamically add more EC2 instances to the shared Kubernetes Cluster. An ALB can be reused by multiple tenants to route traffic to the appropriate pods. For RDS, SaaS providers can use tenant-specific database schemas to separate tenant data. For static data, Amazon Elastic File System (EFS) and tenant-specific directories can be employed. The SaaS provider would still have a control plane AWS account that would now interact with the Kubernetes and AWS APIs to create and update tenant-specific resources.

This transition to a multi-tenant design utilizing Kubernetes, Amazon Elastic Kubernetes Service (EKS), and other managed services offers numerous advantages. It enables efficient resource utilization by leveraging containerization and auto-scaling capabilities, reducing costs, and optimizing performance (see Figure 2).

Multi-tenant configuration

Figure 2. Multi-tenant configuration

EKS cluster sizing and customer segmentation considerations in multi-tenancy designs

A high concentration of SaaS tenants hosted within the same system results in a large “blast radius.” This means a failure within the system has the potential to impact all resident tenants. This situation can lead to downtime for multiple tenants at once. To address this problem, SaaS providers are encouraged to partition their customers amongst multiple AWS accounts, each with their own deployments of this multi-tenant architecture. The number of tenants that can be present in a single cluster is a determination that can only be made by the SaaS provider after weighing the risks. Compare the shared fate of some subset of their customers, against the possible efficiency benefits of a multi-tenant architecture.

EKS security

SaaS providers must evaluate whether it’s appropriate for them to make use of containers as a workload isolation boundary. This is of particular importance in multi-tenant Kubernetes architectures, given that containers running on a single Amazon EC2 instance will share the underlying Linux kernel. Security vulnerabilities place this shared resource (the EC2 instance) at risk from attack vectors from the host Linux instance. Risk is elevated when any container running in a Kubernetes Pod cluster initiates untrusted code. This risk is heightened if SaaS providers permit tenants to “bring their code”. Kubernetes is a single tenant orchestrator, but with a multi-tenant approach to SaaS architectures, a single instance of the Amazon EKS control plane will be shared among all the workloads running within a cluster. Amazon EKS considers the cluster as the hard isolation security boundary. Every Amazon EKS managed Kubernetes cluster is isolated in a dedicated single-tenant Amazon VPC. At present, hard multi-tenancy can only be implemented by provisioning a unique cluster for each tenant.

EFS considerations

A SaaS provider may consider EFS as the storage solution for the static content of the multiple tenants. This provides them with a straightforward, serverless, and elastic file system. Directories may be used to separate the content for each tenant. While this approach of creating tenant-specific directories in EFS provides many benefits, there may be challenges harvesting per-tenant utilization and performance metrics. This can result in operational challenges for providers that need to granularly meter per-tenant usage of resources. Consequently, noisy neighbors will be difficult to identify and remediate. To resolve this, SaaS providers should consider building a custom solution to monitor the individual tenants in the multi-tenant file system by leveraging storage and throughput/IOPS metrics.

RDS considerations

Multi-tenant workloads, where data for multiple customers or end users is consolidated in the same RDS database cluster, can present operational challenges regarding per-tenant observability. Both MySQL Community Edition and open-source PostgreSQL have limited ability to provide per-tenant observability and resource governance. AWS customers operating multi-tenant workloads often use a combination of ‘database’ or ‘schema’ and ‘database user’ accounts as substitutes. AWS customers should use alternate mechanisms to establish a mapping between a tenant and these substitutes. This will give you the ability to process raw observability data from the database engine externally. You can then map these substitutes back to tenants, and distinguish tenants in the observability data.

Conclusion

In this blog, we’ve shown what to consider when moving to a multi-tenancy SaaS solution in the AWS Cloud, how to optimize your cloud-based SaaS design, and some challenges and remediations. Invest effort early in your SaaS design strategy to explore your customer requirements for tenancy. Work backwards from your SaaS tenants end goals. What level of computing performance do they require? What are the required cyber security features? How will you, as the SaaS provider, monitor and operate your platform with the target tenancy configuration? Your respective AWS account team is highly qualified to advise on these design decisions. Take advantage of reviewing and improving your design using the AWS Well-Architected Framework. The tenancy design process should be followed by extensive prototyping to validate functionality before production rollout.

Related information

Prime Day 2023 Powered by AWS – All the Numbers

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/prime-day-2023-powered-by-aws-all-the-numbers/

As part of my annual tradition to tell you about how AWS makes Prime Day possible, I am happy to be able to share some chart-topping metrics (check out my 2016, 2017, 2019, 2020, 2021, and 2022 posts for a look back).

This year I bought all kinds of stuff for my hobbies including a small drill press, filament for my 3D printer, and irrigation tools. I also bought some very nice Alphablock books for my grandkids. According to our official release, the first day of Prime Day was the single largest sales day ever on Amazon and for independent sellers, with more than 375 million items purchased.

Prime Day by the Numbers
As always, Prime Day was powered by AWS. Here are some of the most interesting and/or mind-blowing metrics:

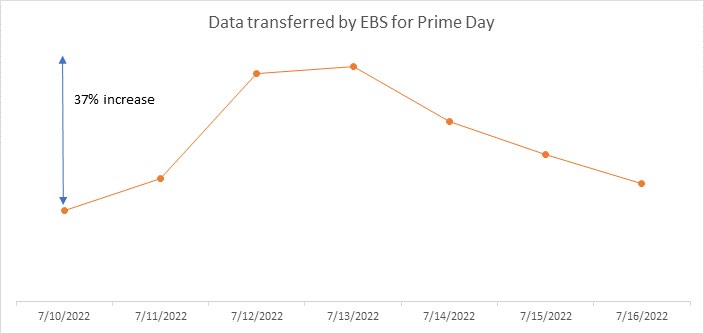
Amazon Elastic Block Store (Amazon EBS) – The Amazon Prime Day event resulted in an incremental 163 petabytes of EBS storage capacity allocated – generating a peak of 15.35 trillion requests and 764 petabytes of data transfer per day. Compared to the previous year, Amazon increased the peak usage on EBS by only 7% Year-over-Year yet delivered +35% more traffic per day due to efficiency efforts including workload optimization using Amazon Elastic Compute Cloud (Amazon EC2) AWS Graviton-based instances. Here’s a visual comparison:

AWS CloudTrail – AWS CloudTrail processed over 830 billion events in support of Prime Day 2023.

Amazon DynamoDB – DynamoDB powers multiple high-traffic Amazon properties and systems including Alexa, the Amazon.com sites, and all Amazon fulfillment centers. Over the course of Prime Day, these sources made trillions of calls to the DynamoDB API. DynamoDB maintained high availability while delivering single-digit millisecond responses and peaking at 126 million requests per second.

Amazon Aurora – On Prime Day, 5,835 database instances running the PostgreSQL-compatible and MySQL-compatible editions of Amazon Aurora processed 318 billion transactions, stored 2,140 terabytes of data, and transferred 836 terabytes of data.

Amazon Simple Email Service (SES) – Amazon SES sent 56% more emails for Amazon.com during Prime Day 2023 vs. 2022, delivering 99.8% of those emails to customers.

Amazon CloudFront – Amazon CloudFront handled a peak load of over 500 million HTTP requests per minute, for a total of over 1 trillion HTTP requests during Prime Day.

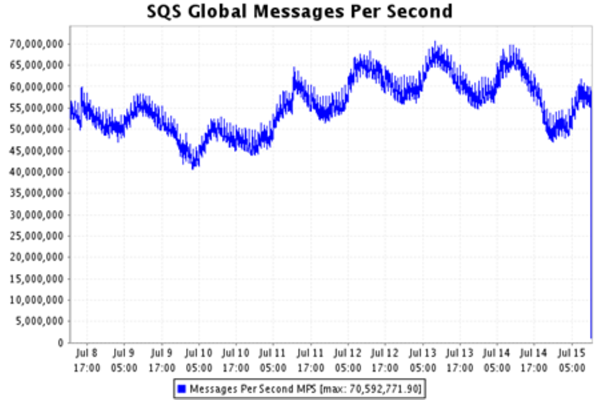
Amazon SQS – During Prime Day, Amazon SQS set a new traffic record by processing 86 million messages per second at peak. This is 22% increase from Prime Day of 2022, where SQS supported 70.5M messages/sec.

Amazon Elastic Compute Cloud (EC2) – During Prime Day 2023, Amazon used tens of millions of normalized AWS Graviton-based Amazon EC2 instances, 2.7x more than in 2022, to power over 2,600 services. By using more Graviton-based instances, Amazon was able to get the compute capacity needed while using up to 60% less energy.

Amazon Pinpoint – Amazon Pinpoint sent tens of millions of SMS messages to customers during Prime Day 2023 with a delivery success rate of 98.3%.

Prepare to Scale
Every year I reiterate the same message: rigorous preparation is key to the success of Prime Day and our other large-scale events. If you are preparing for a similar chart-topping event of your own, I strongly recommend that you take advantage of AWS Infrastructure Event Management (IEM). As part of an IEM engagement, my colleagues will provide you with architectural and operational guidance that will help you to execute your event with confidence!

Jeff;

Deploying an automated Amazon CloudWatch dashboard for AWS Outposts using AWS CDK

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/deploying-an-automated-amazon-cloudwatch-dashboard-for-aws-outposts-using-aws-cdk/

This post is written by Enrico Liguori, Networking Solutions Architect, Hybrid Cloud and Sumeeth Siriyur, Sr. Hybrid Cloud Solutions Architect.

AWS Outposts is a fully managed service that brings the same AWS infrastructure, services, APIs, and tools to virtually any data center, colocation space, manufacturing floor, or on-premises facility where it might be needed. With Outposts, you can run some AWS services on-premises and connect to a broad range of services available in the local AWS Region. Outposts supports workloads requiring low latency, local data processing, data residency, and application migration.

Outposts capacity is driven as per your compute and storage requirements to run workloads. You can monitor Outposts resources using metrics gathered by Amazon CloudWatch. Using these metrics, you can effectively monitor and manage the Outposts resources as they would in the Region, levereging cloud native tools such as CloudWatch dashboards. Check the Monitoring best practices for AWS Outposts blog post to dive deep into the available monitoring options for Outposts.

CloudWatch dashboards are customizable home pages in the CloudWatch console that can be used to monitor resources running on Outposts in a single view. For example, you can monitor in a single pane the number Amazon EC2 instances used per EC2 instance type, the available capacity of Amazon EBS volumes and Amazon S3 buckets, and the operational status of the service link of Outposts.

As a you start deploying additional Outposts resources as a part of their capacity expansion, they must all be integrated and visualized within CloudWatch in an automated way. Traditionally CloudWatch dashboards are built manually and may be time consuming to tune. This post provides also an overview of building CloudWatch dashboards in an automated way using AWS Cloud Development Kit (AWS CDK).

Overview

CloudWatch metrics available to monitor Outposts resources and capacity

CloudWatch metrics for Outposts are available to customers in all public AWS Regions and AWS GovCloud (US) at no additional cost. We can classify the available metrics in two main categories:

To identify the metrics published under the service specific namespaces, we can leverage metadata in the form of tags. A tag is a label that you assign to an AWS resource and consists of a key and an optional value. For the purpose of the monitoring strategy described in this post, we use a tag that contains the OutpostID of the Outpost where the resource is deployed. In this way, we can easily filter the CloudWatch metrics that we would like to show in our dashboard.

To enforce the assignment of tags to our resources we can implement a tagging strategy using AWS tag Policies and Service Control Policies (SCPs).

The following sections describe two different methods to build a CloudWatch dashboard that includes the different types of metrics described so far. In both cases, we see how particularly useful the presence of tags is to identify the service-specific metrics.

Manual approach to building a CloudWatch dashboard for Outposts

This section describes a manual (i.e., non-automated) approach to building a dashboard that could summarize both the capacity utilization metrics and the service specific metrics for your resources running on Outposts.

The benefit of this approach is that we can implement a fully operational dashboard directly from the CloudWatch console. However, it will simultaneously require more effort to properly tune the dashboard to satisfy your monitoring requirements.

You can start creating the dashboard opening the CloudWatch console and following the steps listed in the public documentation.

To display a metric under AWS/Outposts namespace we can choose any of the widgets available. Based on the nature of the data, we can choose different types of Widgets such as Number, Line, Gauge, Explorer, or you can even build your own custom widget.

Together with the Widget type, we must select Outposts namespace in the metric graph dialog box and then navigate to the specific metric of interest.

In case we are creating the dashboard in a different account than the Outposts owner, we must select the right account in the View data drop-down menu to see the Outposts metric in which we are interested.

View data drop-down menu

After selecting one or more metrics we can select Create widget button.

For the service specific metrics, we recommend using the explorer widget. In this way, we can utilize the tagging strategy described earlier to automatically identify the metrics belonging to the resources running on Outposts. Check the documentation page for a step-by-step guide for creating an explorer widget based on tags.

Automated outpost dashboard

After we’ve seen how to build a dashboard manually from the console, in this secton we describe an automated approach to deploy a dashboard for Outposts through AWS CDK.

AWS CDK is an open source software development framework to model and provision your cloud application resources using familiar programming languages, including TypeScript, JavaScript, Python, C#, and Java. For the solution in this post, we use Python.

Architecture overview

The AWS CDK stack described in this post, assumes that the resources running on Outposts (EC2 instances, S3 buckets, Application Load Balancers (ALBs), and RDS instances) are tagged using the tagging strategy described earlier.

Specifying a tag name and a tag value in a configuration file automatically discovers the resources with that tag and adds the related metrics to the CloudWatch dashboard.

Together with the service specific metrics, it creates a series of widgets that we can use to monitor the capacity available and utilized in each Outpost that belongs to the account where the script is running.

The workflow is made of the following phases:

  1. The AWS CDK stack creates an AWS CodeCommit repository and uploads its own code into it. The code contains a series of modules, one for each section of the CloudWatch dashboard. A section of the dashboard contains one or more widgets showing the metrics of a specific service.
  2. To maintain the CloudWatch dashboard always up-to-date with the resources matching the tag, it creates a pipeline in AWS CodePipeline that can dynamically create and or update the dashboard. The pipeline runs the code in the CodeCommit repository and is made of two stages. In the first one, the build stage, it builds the dependencies needed by the AWS CDK stack. In the second stage, the Deploy stage, it loads and runs the modules used to build the dashboard.
  3. Each module contains the code to automatically discover the tagged resources of a specific service. This discovery phase uses standard AWS APIs called through the Python SDK Boto3.
  4. Based on the results of the discovery phase, AWS CDK produces an AWS CloudFormation template containing the definition of the CloudWatch dashboard sections. The template is submitted to CloudFormation.
  5. CloudFormation creates or, if already defined, updates the CloudWatch dashboard.
  6. Together with the dashboard, the AWS CDK script also contains the definition of a CloudWatch Event that, once deployed, triggers the pipeline each time a resource tagged with the specified tag is created or destroyed.

Prerequisites

To implement the solution presented in this post, you must configure:

  1. git as distributed version control system.
  2. In case it is the first time that you’re using AWS CDK in this account and region, you must:

a. Install the AWS CDK, and its prerequisites, following these instructions.

b. Go through the AWS CDK bootstrapping process. This is required only for the first time that we use AWS CDK in a specific AWS environment (an AWS environment is a combination of an AWS account and Region).

How to install

Step 1: Clone the AWS CDK code hosted on GitHub with:

$ git clone https://github.com/aws-samples/automated-cloudwatch-dashboard.git

Step 2: enter the directory using the following:

$ cd  automated-cloudwatch-dashboard/

Step 3: Install the needed Python dependencies with:

$ pip install -r requirements.txt

Step 4: Modify the configuration file

Before deploying the stack, we must modify the configuration file to specify the tag we use for identifying our resources running on Outposts. Open the file with the name config.yaml with your preferred text editor and specify:

      • A name for the dashboard. The default name used is Automated-CloudWatch-Dashboard.
      • Replace <tag_name> placeholder following the tag_name variable with the tag name used to tag the resources that you want to include in the dashboard.
      • Replace <tag_value> placeholder under tag_values variable with the tag value that you used.

Here is an example config.yaml configuration file:

dashboard_name: Automated-CloudWatch-Dahsboard
tag_name: OutpostID
tag_values:
  - op-1234567890abcdefg 

Stack deployment

We can deploy the stack with the following:

$ cdk deploy

At the end of the deployment process, the pipeline that creates the dashboard is provisioned. You can now go to your CloudWatch console to view it.

Automated Outposts dashboard overview

Now that we have built our dashboard, let’s review each section:

  1. Outpost capacity

Outpost Capacity diagram

The AWS CDK stacks define a capacity section for each Outpost available to the AWS account where the script runs.

In this section, we find four widgets showing metrics published under the AWS/Outpost namespace. The first widget shows for each EC2 instance type available on the Outposts the number of instances utilized and available for that instance type. In the second row, we can visualize the available capacity for the Amazon EBS volumes and for the S3 buckets. The last widget shows the operational status of the service link of Outposts.

2. EC2 instances

CPU, Network, and Disk Utilization for an EC2 instance diagram

In this section of the dashboard, we find the metrics showing the CPU, Network, and Disk Utilization for an EC2 instance. It has defined a section of this type for each EC2 instance with a tag assigned matching the name and the value specified in the configuration file of the script.

3. Application Load Balancer

The ALB section aggregates metrics showing the operational status of a load balancer hosted on Outposts

The ALB section aggregates metrics showing the operational status of a load balancer hosted on Outposts. A section of this type is defined for each ALB with an assigned tag matching the one specified in the configuration file.

4. S3 buckets

The S3 buckets section diagram

The S3 buckets section is defined only once and aggregates the utilization metrics for all S3 buckets with an assigned tag.

5. AutoScaling group

The AutoScaling group section diagram

The AutoScaling group section can be used to monitor the number of instances in service in a specific AS group with a tag assigned. This section is defined once and can aggregate the metrics for multiple AutoScaling groups.

Clean up

To terminate the resources that we created in this post, run the following:

$ cdk destroy

Then, go to the Cloudformation console and delete the stack with the name “Deploy-AutomatedCloudWatchDashboard”.

Conclusion

In conclusion, this post demonstrates a manual way of creating CloudWatch Metrics dashboard using the CloudWatch console and an automated way using AWS CDK. The automated approach is also scalable by automatically discovering any new resources added to the existing Outposts in the your environment without any changes to the code.

Quick Restoration through Replacing the Root Volumes of Amazon EC2 instances

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/quick-restoration-through-replacing-the-root-volumes-of-amazon-ec2/

This blog post is written by Katja-Maja Krödel, IoT Specialist Solutions Architect, and Benjamin Meyer, Senior Solutions Architect, Game Tech.

Customers use Amazon Elastic Compute Cloud (Amazon EC2) instances to develop, deploy, and test applications. To use those instances most effectively, customers have expressed the need to set back their instance to a previous state within minutes or even seconds. They want to find a quick and automated way to manage setting back their instances at scale.

The feature of replacing Root Volumes of Amazon EC2 instances enables customers to replace the root volumes of running EC2 instances to a specific snapshot or its launch state. Without stopping the instance, this allows customers to fix issues while retaining the instance store data, networking, and AWS Identity and Access Management (IAM) configuration. Customers can resume their operations with their instance store data intact. This works for all virtualized EC2 instances and bare metal EC2 Mac instances today.

In this post, we show you how to design your architecture for automated Root Volume Replacement using this Amazon EC2 feature. We start with the automated snapshot creation, continue with automatically replacing the root volume, and finish with how to keep your environment clean after your replacement job succeeds.

What is Root Volume Replacement?

Amazon EC2 enables customers to replace the root Amazon Elastic Block Store (Amazon EBS) volume for an instance without stopping the instance to which it’s attached. An Amazon EBS root volume is replaced to the launch state, or any snapshot taken from the EBS volume itself. This allows issues to be fixed, such as root volume corruption or guest OS networking errors. Replacing the root volume of an instance includes the following steps:

  • A new EBS volume is created from a previously taken snapshot or the launch state
  • Reboot of the instance
  • While rebooting, the current root volume is detached and the new root volume is attached

The previous EBS root volume isn’t deleted and can be attached to an instance for later investigation of the volume. If replacing to a different state of the EBS than the launch state, then a snapshot of the current root volume is used.

An example use case is a continuous integration/continuous deployment (CI/CD) System that builds on EC2 instances to build artifacts. Within this system, you could alter the installed tools on the host and may cause failing builds on the same machine. To prevent any unclean builds, the introduced architecture is used to clean up the machine by replacing the root volume to a previously known good state. This is especially interesting for EC2 Mac Instances, as their Dedicated Host won’t undergo the scrubbing process, and the instance is more quickly restored than launching a fresh EC2 Mac instance on the same host.

Overview

The feature of replacing Root Volumes was introduced in April 2021 and has just been <TBD> extended to work for Bare Metal EC2 Mac Instances. This means that EC2 Mac Instances are included. If you want to reset an EC2 instance to a previously known good state, then you can create Snapshots of your EBS volumes. To reset the root volume to its launch state, no snapshot is needed. For non-root volumes, you can use these Snapshots to create new EBS volumes, and then attach those to your instance as well as detach them. To automate the process of replacing your root volume not only once, but also in a repeatable manner, we’re introducing you to an architecture that can fully-automate this process.

In the case that you use a snapshot to create a new root volume, you must take a new snapshot of that volume to be able to get back to that state later on. You can’t use a snapshot of a different volume to restore to, which is the reason that the architecture includes the automatic snapshot creation of a fresh root volume.

The architecture is built in three steps:

  1. Automation of Snapshot Creation for new EBS volumes
  2. Automation of replacing your Root Volume
  3. Preparation of the environment for the next Root Volume Replacement

The following diagram illustrates the architecture of this solution.

 Architecture of the automated creation of Root Volumes for Amazon EC2 Instances

In the next sections, we go through these concepts to design the automatic Root Volume Replacement Task.

Automation of Snapshot Creation for new EBS volumes

Architecture of the automated creation of Snapshots of new EBS Volumes.

The figure above illustrates the architecture for automatically creating a snapshot of an existing EBS volume. In this architecture, we focus on the automation of creating a snapshot whenever a new EBS root volume is created.

Amazon EventBridge is used to invoke an AWS Lambda function on an emitted createVolume event. For automated reaction to the event, you can add a rule to the EventBridge which will forward the event to an AWS Lambda function whenever a new EBS volume is created. The rule within EventBridge looks like this:

{
  "source": ["aws.ec2"],
  "detail-type": ["EBS Volume Notification"],
  "detail": {
    "event": ["createVolume"]
  }
}

An example event is emitted when an EBS root volume is created, which will then invoke the Lambda function to look like this:

{
   "version": "0",
   "id": "01234567-0123-0123-0123-012345678901",
   "detail-type": "EBS Volume Notification",
   "source": "aws.ec2",
   "account": "012345678901",
   "time": "yyyy-mm-ddThh:mm:ssZ",
   "region": "us-east-1",
   "resources": [
      "arn:aws:ec2:us-east-1:012345678901:volume/vol-01234567"
   ],
   "detail": {
      "result": "available",
      "cause": "",
      "event": "createVolume",
      "request-id": "01234567-0123-0123-0123-0123456789ab"
   }
}

The code of the function uses the resource ARN within the received event and requests resource details about the EBS volume from the Amazon EC2 APIs. Since the event doesn’t include information if it’s a root volume, then you must verify this using the Amazon EC2 API.

The following is a summary of the tasks of the Lambda function:

  1. Extract the EBS ARN from the EventBridge Event
  2. Verify that it’s a root volume of an EC2 Instance
  3. Call the Amazon EC2 API create-snapshot to create a snapshot of the root volume and add a tag replace-snapshot=true

Then, the tag is used to clean up the environment and get rid of snapshots that aren’t needed.

As an alternative, you can emit your own event to EventBridge. This can be used to automatically create snapshots to which you can restore your volume. Instead of reacting to the createVolume event, you can use a customized approach for this architecture.

Automation of replacing your Root Volume

Architecture of the automated creation of Snapshots of new EBS Volumes.

The figure above illustrates the procedure of replacing the EBS root volume. It starts with the event, which is created through the AWS Command Line Interface (AWS CLI), console, or usage of the API. This leads to creating a new volume from a snapshot or using the initial launch state. The EC2 instance is rebooted, and during that time the old root volume is detached and a new volume gets attached as the root volume.

To invoke the create-replace-root-volume-task, you can call the Amazon EC2 API with the following AWS CLI command:

aws ec2 create-replace-root-volume-task --instance-id <value> --snapshot <value> --tag-specifications ResourceType=string,Tags=[{Key=replaced-volume,Value=true}]

If you want to restore to launch state, then omit the --snapshot parameter:

aws ec2 create-replace-root-volume-task --instance-id <value> --tag-specifications ResourceType=string,Tags=[{Key=delete-volume,Value=true}]

After running this command, AWS will create a new EBS volume, add the tag to the old EBS replaced-volume=true, restart your instance, and attach the new volume to the instance as the root volume. The tag is used later to detect old root volumes and clean up the environment.

If this is combined with the earlier explained automation, then the automation will immediately take a snapshot from the new EBS volume. A restore operation can only be done to a snapshot of the current EBS root volume. Therefore, if no snapshot is taken from the freshly restored EBS volume, then no restore operation is possible except the restore to launch state.

Preparation of the Environment for the next Root Volume Replacement

After the task is completed, the old root volume isn’t removed. Additionally, snapshots of previous root volumes can’t be used to restore current root volumes. To clean up your environment, you can schedule a Lambda function which does the following steps:

  • Delete detached EBS volumes with the tag delete-volume=true
  • Delete snapshots with the tag replace-snapshot=true, which aren’t associated with an existing EBS volume

Conclusion

In this post, we described an architecture to quickly restore EC2 instances through Root Volume Replacement. The feature of replacing Root Volumes of Amazon EC2 instances, now including Bare Metal EC2 Mac instances, enables customers to replace the root volumes of running EC2 instances to a specific snapshot or its launch state. Customers can resume their operations with their instance store data intact. We’ve split the process of doing this in an automated and quick manner into three steps: Create a snapshot, run the replacement task, and reset your environment to be prepared for a following replacement task. If you want to learn more about this feature, then see the Announcement of replacing Root Volumes, as well as the documentation for this feature. <TBD Announcement Bare Metal>

Let’s Architect! Optimizing the cost of your architecture

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-optimizing-the-cost-of-your-architecture/

Written in collaboration with Ben Moses, AWS Senior Solutions Architect, and Michael Holtby, AWS Senior Manager Solutions Architecture


Designing an architecture is not a simple task. There are many dimensions and characteristics of a solution to consider, such as the availability, performance, or resilience.

In this Let’s Architect!, we explore cost optimization and ideas on how to rethink your AWS workloads, providing suggestions that span from compute to data transfer.

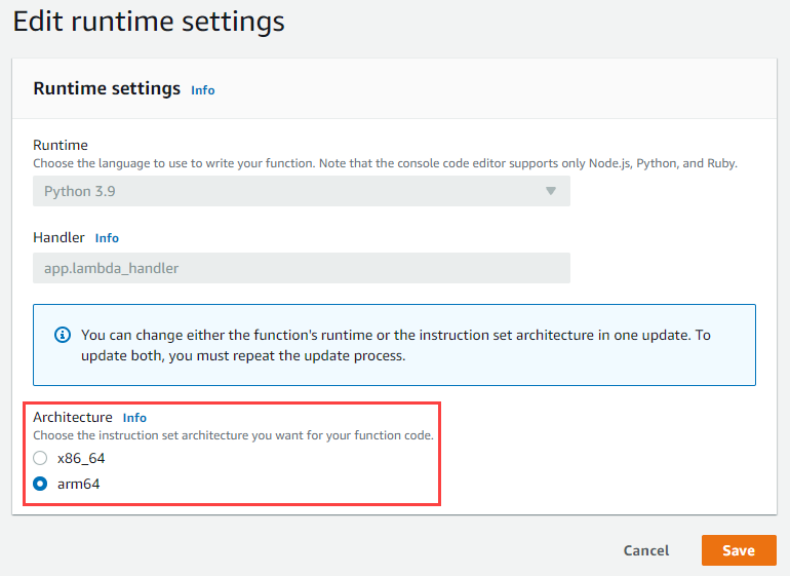
Migrating AWS Lambda functions to Arm-based AWS Graviton2 processors

AWS Graviton processors are custom silicon from Amazon’s Annapurna Labs. Based on the Arm processor architecture, they are optimized for performance and cost, which allows customers to get up to 34% better price performance.

This AWS Compute Blog post discusses some of the differences between the x86 and Arm architectures, as well as methods for developing Lambda functions on Graviton2, including performance benchmarking.

Many serverless workloads can benefit from Graviton2, especially when they are not using a library that requires an x86 architecture to run.

Take me to this Compute post!

Choosing Graviton2 for AWS Lambda function in the AWS console

Choosing Graviton2 for AWS Lambda function in the AWS console

Key considerations in moving to Graviton2 for Amazon RDS and Amazon Aurora databases

Amazon Relational Database Service (Amazon RDS) and Amazon Aurora support a multitude of instance types to scale database workloads based on needs. Both services now support Arm-based AWS Graviton2 instances, which provide up to 52% price/performance improvement for Amazon RDS open-source databases, depending on database engine, version, and workload. They also provide up to 35% price/performance improvement for Amazon Aurora, depending on database size.

This AWS Database Blog post showcases strategies for updating RDS DB instances to make use of Graviton2 with minimal changes.

Take me to this Database post!

Choose your instance class that leverages Graviton2, such as db.r6g.large (the “g” stands for Graviton2)

Choose your instance class that leverages Graviton2, such as db.r6g.large (the “g” stands for Graviton2)

Overview of Data Transfer Costs for Common Architectures

Data transfer charges are often overlooked while architecting an AWS solution. Considering data transfer charges while making architectural decisions can save costs. This AWS Architecture Blog post describes the different flows of traffic within a typical cloud architecture, showing where costs do and do not apply. For areas where cost applies, it shows best-practice strategies to minimize these expenses while retaining a healthy security posture.

Take me to this Architecture post!

Accessing AWS services in different Regions

Accessing AWS services in different Regions

Improve cost visibility and re-architect for cost optimization

This Architecture Blog post is a collection of best practices for cost management in AWS, including the relevant tools; plus, it is part of a series on cost optimization using an e-commerce example.

AWS Cost Explorer is used to first identify opportunities for optimizations, including data transfer, storage in Amazon Simple Storage Service and Amazon Elastic Block Store, idle resources, and the use of Graviton2 (Amazon’s Arm-based custom silicon). The post discusses establishing a FinOps culture and making use of Service Control Policies (SCPs) to control ongoing costs and guide deployment decisions, such as instance-type selection.

Take me to this Architecture post!

Applying SCPs on different environments for cost control

Applying SCPs on different environments for cost control

See you next time!

Thanks for joining us to discuss optimizing costs while architecting! This is the last Let’s Architect! post of 2022. We will see you again in 2023, when we explore even more architecture topics together.

Wishing you a happy holiday season and joyous new year!

Can’t get enough of Let’s Architect!?

Visit the Let’s Architect! page of the AWS Architecture Blog for access to the whole series.

Looking for more architecture content?

AWS Architecture Center provides reference architecture diagrams, vetted architecture solutions, Well-Architected best practices, patterns, icons, and more!

Deploying IBM Cloud Pak for integration on Red Hat OpenShift Service on AWS

Post Syndicated from Eduardo Monich Fronza original https://aws.amazon.com/blogs/architecture/deploying-ibm-cloud-pak-for-integration-on-red-hat-openshift-service-on-aws/

Customers across many industries use IBM integration software, such as IBM MQ, DataPower, API Connect, and App Connect, as the backbone that integrates and orchestrates their business-critical workloads.

These customers often tell Amazon Web Services (AWS), they want to migrate their applications to AWS Cloud, as part of their business strategy: to lower costs, gain agility, and innovate faster.

In this blog, we will explore how customers, who are looking at ways to run IBM software on AWS, can use Red Hat OpenShift Service on AWS (ROSA) to deploy IBM Cloud Pak for Integration (CP4I) with modernized versions of IBM integration products.

As ROSA is a fully managed OpenShift service that is jointly supported by AWS and Red Hat, plus managed by Red Hat site reliability engineers, customers benefit from not having to manage the lifecycle of Red Hat OpenShift Container Platform (OCP) clusters.

This post explains the steps to:

  • Create a ROSA cluster
  • Configure persistent storage
  • Install CP4I and the IBM MQ 9.3 operator

Cloud Pak for integration architecture

In this blog, we are implementing a highly available ROSA cluster with three Availability Zones (AZ), three master nodes, three infrastructure nodes, and three worker nodes.

Review the AWS documentation for Regions and AZs and the regions where ROSA is available to choose the best region for your deployment.

Figure 1 demonstrates the solution’s architecture.

IBM Cloud Pak for Integration on ROSA architecture

Figure 1. IBM Cloud Pak for Integration on ROSA architecture

In our scenario, we are building a public ROSA cluster, with an internet-facing Classic Load Balancer providing access to Ports 80 and 443. Consider using a ROSA private cluster when you are deploying CP4I in your AWS account.

We are using Amazon Elastic File System (Amazon EFS) and Amazon Elastic Block Store (Amazon EBS) for our cluster’s persistent storage. Review the IBM CP4I documentation for information about supported AWS storage options.

Review AWS prerequisites for ROSA and AWS Security best practices in IAM documentation, before deploying CP4I for production workloads, to protect your AWS account and resources.

Cost

You are responsible for the cost of the AWS services used when deploying CP4I in your AWS account. For cost estimates, see the pricing pages for each AWS service you use.

Prerequisites

Before getting started, review the following prerequisites:

Installation steps

To deploy CP4I on ROSA, complete the following steps:

  1. From the AWS ROSA console, click Enable ROSA to active the service on your AWS account (Figure 2).

    Enable ROSA on your AWS account

    Figure 2. Enable ROSA on your AWS account

  2. Create an AWS Cloud9 environment to run your CP4I installation. We used a t3.small instance type.
  3. When it comes up, close the Welcome tab and open a new Terminal tab to install the required packages:
    curl "https://awscli.amazonaws.com/awscli-exe-linux-x86_64.zip" -o "awscliv2.zip"
    unzip awscliv2.zip
    sudo ./aws/install
    wget https://mirror.openshift.com/pub/openshift-v4/clients/rosa/latest/rosa-linux.tar.gz
    sudo tar -xvzf rosa-linux.tar.gz -C /usr/local/bin/
    
    rosa download oc
    sudo tar -xvzf openshift-client-linux.tar.gz -C /usr/local/bin/
    
    sudo yum -y install jq gettext
  4. Ensure the ELB service-linked role exists in your AWS account:
    aws iam get-role --role-name 
    "AWSServiceRoleForElasticLoadBalancing" || aws iam create-service-linked-role --aws-service-name 
    "elasticloadbalancing.amazonaws.com"
  5. Create an IAM policy named cp4i-installer-permissions with the following permissions:
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": [
                    "autoscaling:*",
                    "cloudformation:*",
                    "cloudwatch:*",
                    "ec2:*",
                    "elasticfilesystem:*",
                    "elasticloadbalancing:*",
                    "events:*",
                    "iam:*",
                    "kms:*",
                    "logs:*",
                    "route53:*",
                    "s3:*",
                    "servicequotas:GetRequestedServiceQuotaChange",
                    "servicequotas:GetServiceQuota",
                    "servicequotas:ListServices",
                    "servicequotas:ListServiceQuotas",
                    "servicequotas:RequestServiceQuotaIncrease",
                    "sts:*",
                    "support:*",
                    "tag:*"
                ],
                "Resource": "*"
            }
        ]
    }
  6. Create an IAM role:
    1. Select AWS service and EC2, then click Next: Permissions.
    2. Select the cp4i-installer-permissions policy, and click Next.
    3. Name it cp4i-installer, and click Create role.
  7. From your AWS Cloud9 IDE, click the grey circle button on the top right, and select Manage EC2 Instance (Figure 3).

    Manage the AWS Cloud9 EC2 instance

    Figure 3. Manage the AWS Cloud9 EC2 instance

  8. On the Amazon EC2 console, select the AWS Cloud9 instance, then choose Actions / Security / Modify IAM Role.
  9. Choose cp4i-installer from the IAM Role drop down, and click Update IAM role (Figure 4).

    Attach the IAM role to your workspace

    Figure 4. Attach the IAM role to your workspace

  10. Update the IAM settings for your AWS Cloud9 workspace:
    aws cloud9 update-environment --environment-id $C9_PID --managed-credentials-action DISABLE
    rm -vf ${HOME}/.aws/credentials
  11. Configure the following environment variables:
    export ACCOUNT_ID=$(aws sts get-caller-identity --output text --query Account)
    export AWS_REGION=$(curl -s 169.254.169.254/latest/dynamic/instance-identity/document | jq -r '.region')
    export ROSA_CLUSTER_NAME=cp4iblog01
  12. Configure the aws cli default region:
    aws configure set default.region ${AWS_REGION}
  13. Navigate to the Red Hat Hybrid Cloud Console, and copy your OpenShift Cluster Manager API Token.
  14. Use the token and log in to your Red Hat account:
    rosa login --token=<your_openshift_api_token>
  15. Verify that your AWS account satisfies the quotas to deploy your cluster:
    rosa verify quota
  16. When deploying ROSA for the first time, create the account-wide roles:
    rosa create account-roles --mode auto --yes
  17. Create your ROSA cluster:
    rosa create cluster --cluster-name $ROSA_CLUSTER_NAME --sts \
      --multi-az \
      --region $AWS_REGION \
      --version 4.10.35 \
      --compute-machine-type m5.4xlarge \
      --compute-nodes 3 \
      --operator-roles-prefix cp4irosa \
      --mode auto --yes \
      --watch
  18. Once your cluster is ready, create a cluster-admin user (it takes approximately 5 minutes):
    rosa create admin --cluster=$ROSA_CLUSTER_NAME
  19. Log in to your cluster using the cluster-admin credentials. You can copy the command from the output of the previous step. For example:
    oc login https://<your_cluster_api_address>:6443 \
      --username cluster-admin \
      --password <your_cluster-admin_password>
  20. Create an IAM policy allowing ROSA to use Amazon EFS:
    cat <<EOF > $PWD/efs-policy.json
    {
      "Version": "2012-10-17",
      "Statement": [
     {
       "Effect": "Allow",
       "Action": [
         "elasticfilesystem:DescribeAccessPoints",
         "elasticfilesystem:DescribeFileSystems"
       ],
       "Resource": "*"
     },
     {
       "Effect": "Allow",
       "Action": [
         "elasticfilesystem:CreateAccessPoint"
       ],
       "Resource": "*",
       "Condition": {
         "StringLike": {
           "aws:RequestTag/efs.csi.aws.com/cluster": "true"
         }
       }
     },
     {
       "Effect": "Allow",
       "Action": "elasticfilesystem:DeleteAccessPoint",
       "Resource": "*",
       "Condition": {
         "StringEquals": {
           "aws:ResourceTag/efs.csi.aws.com/cluster": "true"
         }
       }
     }
      ]
    }
    EOF
    POLICY=$(aws iam create-policy --policy-name "${ROSA_CLUSTER_NAME}-cp4i-efs-csi" --policy-document file://$PWD/efs-policy.json --query 'Policy.Arn' --output text) || POLICY=$(aws iam list-policies --query 'Policies[?PolicyName==`cp4i-efs-csi`].Arn' --output text)
  21. Create an IAM trust policy:
    export OIDC_PROVIDER=$(oc get authentication.config.openshift.io cluster -o json | jq -r .spec.serviceAccountIssuer| sed -e "s/^https:\/\///")
    cat <<EOF > $PWD/TrustPolicy.json
    {
      "Version": "2012-10-17",
      "Statement": [
     {
       "Effect": "Allow",
       "Principal": {
         "Federated": "arn:aws:iam::${ACCOUNT_ID}:oidc-provider/${OIDC_PROVIDER}"
       },
       "Action": "sts:AssumeRoleWithWebIdentity",
       "Condition": {
         "StringEquals": {
           "${OIDC_PROVIDER}:sub": [
             "system:serviceaccount:openshift-cluster-csi-drivers:aws-efs-csi-driver-operator",
             "system:serviceaccount:openshift-cluster-csi-drivers:aws-efs-csi-driver-controller-sa"
           ]
         }
       }
     }
      ]
    }
    EOF
  22. Create an IAM role with the previously created policies:
    ROLE=$(aws iam create-role \
      --role-name "${ROSA_CLUSTER_NAME}-aws-efs-csi-operator" \
      --assume-role-policy-document file://$PWD/TrustPolicy.json \
      --query "Role.Arn" --output text)
    aws iam attach-role-policy \
      --role-name "${ROSA_CLUSTER_NAME}-aws-efs-csi-operator" \
      --policy-arn $POLICY
  23. Create an OpenShift secret to store the AWS access keys:
    cat <<EOF | oc apply -f -
    apiVersion: v1
    kind: Secret
    metadata:
      name: aws-efs-cloud-credentials
      namespace: openshift-cluster-csi-drivers
    stringData:
      credentials: |-
        [default]
        role_arn = $ROLE
        web_identity_token_file = /var/run/secrets/openshift/serviceaccount/token
    EOF
  24. Install the Amazon EFS CSI driver operator:
    cat <<EOF | oc create -f -
    apiVersion: operators.coreos.com/v1
    kind: OperatorGroup
    metadata:
      generateName: openshift-cluster-csi-drivers-
      namespace: openshift-cluster-csi-drivers
    ---
    apiVersion: operators.coreos.com/v1alpha1
    kind: Subscription
    metadata:
      labels:
        operators.coreos.com/aws-efs-csi-driver-operator.openshift-cluster-csi-drivers: ""
      name: aws-efs-csi-driver-operator
      namespace: openshift-cluster-csi-drivers
    spec:
      channel: stable
      installPlanApproval: Automatic
      name: aws-efs-csi-driver-operator
      source: redhat-operators
      sourceNamespace: openshift-marketplace
    EOF
  25. Track the operator installation:
    watch oc get deployment aws-efs-csi-driver-operator \
     -n openshift-cluster-csi-drivers
  26. Install the AWS EFS CSI driver:
    cat <<EOF | oc apply -f -
    apiVersion: operator.openshift.io/v1
    kind: ClusterCSIDriver
    metadata:
      name: efs.csi.aws.com
    spec:
      managementState: Managed
    EOF
  27. Wait until the CSI driver is running:
    watch oc get daemonset aws-efs-csi-driver-node \
     -n openshift-cluster-csi-drivers
  28. Create a rule allowing inbound NFS traffic from your cluster’s VPC Classless Inter-Domain Routing (CIDR):
    NODE=$(oc get nodes --selector=node-role.kubernetes.io/worker -o jsonpath='{.items[0].metadata.name}')
    VPC_ID=$(aws ec2 describe-instances --filters "Name=private-dns-name,Values=$NODE" --query 'Reservations[*].Instances[*].{VpcId:VpcId}' | jq -r '.[0][0].VpcId')
    CIDR=$(aws ec2 describe-vpcs --filters "Name=vpc-id,Values=$VPC_ID" --query 'Vpcs[*].CidrBlock' | jq -r '.[0]')
    SG=$(aws ec2 describe-instances --filters "Name=private-dns-name,Values=$NODE" --query 'Reservations[*].Instances[*].{SecurityGroups:SecurityGroups}' | jq -r '.[0][0].SecurityGroups[0].GroupId')
    aws ec2 authorize-security-group-ingress \
      --group-id $SG \
      --protocol tcp \
      --port 2049 \
      --cidr $CIDR | jq .
  29. Create an Amazon EFS file system:
    EFS_FS_ID=$(aws efs create-file-system --performance-mode generalPurpose --encrypted --region ${AWS_REGION} --tags Key=Name,Value=ibm_cp4i_fs | jq -r '.FileSystemId')
    SUBNETS=($(aws ec2 describe-subnets --filters "Name=vpc-id,Values=${VPC_ID}" "Name=tag:Name,Values=*${ROSA_CLUSTER_NAME}*private*" | jq --raw-output '.Subnets[].SubnetId'))
    for subnet in ${SUBNETS[@]}; do
      aws efs create-mount-target \
        --file-system-id $EFS_FS_ID \
        --subnet-id $subnet \
        --security-groups $SG
    done
  30. Create an Amazon EFS storage class:
    cat <<EOF | oc apply -f -
    kind: StorageClass
    apiVersion: storage.k8s.io/v1
    metadata:
      name: efs-sc
    provisioner: efs.csi.aws.com
    parameters:
      provisioningMode: efs-ap
      fileSystemId: $EFS_FS_ID
      directoryPerms: "750"
      gidRangeStart: "1000"
      gidRangeEnd: "2000"
      basePath: "/ibm_cp4i_rosa_fs"
    EOF
  31. Add the IBM catalog sources to OpenShift:
    cat <<EOF | oc apply -f -
    apiVersion: operators.coreos.com/v1alpha1
    kind: CatalogSource
    metadata:
      name: ibm-operator-catalog
      namespace: openshift-marketplace
    spec:
      displayName: IBM Operator Catalog
      image: 'icr.io/cpopen/ibm-operator-catalog:latest'
      publisher: IBM
      sourceType: grpc
      updateStrategy:
        registryPoll:
          interval: 45m
    EOF
  32. Get the console URL of your ROSA cluster:
    rosa describe cluster --cluster=$ROSA_CLUSTER_NAME | grep Console
  33. Copy your entitlement key from the IBM container software library.
  34. Log in to your ROSA web console, navigate to Workloads > Secrets.
  35. Set the project to openshift-config; locate and click pull-secret (Figure 5).

    Edit the pull-secret entry

    Figure 5. Edit the pull-secret entry

  36. Expand Actions and click Edit Secret.
  37. Scroll to the end of the page, and click Add credentials (Figure 6):
    1. Registry server address: cp.icr.io
    2. Username field: cp
    3. Password: your_ibm_entitlement_key

      Configure your IBM entitlement key secret

      Figure 6. Configure your IBM entitlement key secret


  38. Next, navigate to Operators > OperatorHub. On the OperatorHub page, use the search filter to locate the tile for the operators you plan to install: IBM Cloud Pak for Integration and IBM MQ. Keep all values as default for both installations (Figure 7). For example, IBM Cloud Pak for Integration:

    Figure 7. Install CP4I operators

    Figure 7. Install CP4I operators

  39. Create a namespace for each CP4I workload that will be deployed. In this blog, we’ve created for the platform UI and IBM MQ:
    oc new-project integration
    oc new-project ibm-mq
  40. Review the IBM documentation to select the appropriate license for your deployment.
  41. Deploy the platform UI:
    cat <<EOF | oc apply -f -
    apiVersion: integration.ibm.com/v1beta1
    kind: PlatformNavigator
    metadata:
      name: integration-quickstart
      namespace: integration
    spec:
      license:
        accept: true
        license: L-RJON-CD3JKX
      mqDashboard: true
      replicas: 3  # Number of replica pods, 1 by default, 3 for HA
      storage:
        class: efs-sc
      version: 2022.2.1
    EOF
  42. Track the deployment status, which takes approximately 40 minutes:
    watch oc get platformnavigator -n integration
  43. Create an IBM MQ queue manager instance:
    cat <<EOF | oc apply -f -
    apiVersion: mq.ibm.com/v1beta1
    kind: QueueManager
    metadata:
      name: qmgr-inst01
      namespace: ibm-mq
    spec:
      license:
        accept: true
        license: L-RJON-CD3JKX
        use: NonProduction
      web:
        enabled: true
      template:
        pod:
          containers:
            - env:
                - name: MQSNOAUT
                  value: 'yes'
              name: qmgr
      queueManager:
        resources:
          limits:
            cpu: 500m
          requests:
            cpu: 500m
        availability:
          type: SingleInstance
        storage:
          queueManager:
            type: persistent-claim
            class: gp3
            deleteClaim: true
            size: 2Gi
          defaultClass: gp3
        name: CP4IQMGR
      version: 9.3.0.1-r1
    EOF
  44. Check the status of the queue manager:
    oc describe queuemanager qmgr-inst01 -n ibm-mq

Validation steps

Let’s verify our installation!

  1. Run the commands to retrieve the CP4I URL and administrator password:
    oc describe platformnavigator integration-quickstart \
      -n integration | grep "^.*UI Endpoint" | xargs | cut -d ' ' -f3
    oc get secret platform-auth-idp-credentials \
      -n ibm-common-services -o jsonpath='{.data.admin_password}' \
      | base64 -d && echo
  2. Using the information from the previous step, access your CP4I web console.
  3. Select the option to authenticate with the IBM provided credentials (admin only) to login with your admin password.
  4. From the CP4I console, you can manage users and groups allowed to access the platform, install new operators, and view the components that are installed.
  5. Click qmgr-inst01 in the Messaging widget to bring up your IBM MQ setup (Figure 8).

    CP4I console features

    Figure 8. CP4I console features

  6. In the Welcome to IBM MQ panel, click the CP4IQMGR queue manager. This shows the state, resources, and allows you to configure your instances (Figure 9).

    Queue manager details

    Figure 9. Queue manager details

Congratulations! You have successfully deployed IBM CP4I on Red Hat OpenShift on AWS.

Post installation

Review the following topics, when you are installing CP4I on production environments:

Cleanup

Connect to your Cloud9 workspace, and run the following steps to delete the CP4I installation, including ROSA. This avoids incurring future charges on your AWS account:

EFS_EF_ID=$(aws efs describe-file-systems \
  --query 'FileSystems[?Name==`ibm_cp4i_fs`].FileSystemId' \
  --output text)
MOUNT_TARGETS=$(aws efs describe-mount-targets --file-system-id $EFS_EF_ID --query 'MountTargets[*].MountTargetId' --output text)
for mt in ${MOUNT_TARGETS[@]}; do
  aws efs delete-mount-target --mount-target-id $mt
done
aws efs delete-file-system --file-system-id $EFS_EF_ID

rosa delete cluster -c $ROSA_CLUSTER_NAME --yes --region $AWS_REGION

Monitor your cluster uninstallation logs, run:

rosa logs uninstall -c $ROSA_CLUSTER_NAME --watch

Once the cluster is uninstalled, remove the operator-roles and oidc-provider, as informed in the output of the rosa delete command. For example:

rosa delete operator-roles -c 1vepskr2ms88ki76k870uflun2tjpvfs --mode auto –yes
rosa delete oidc-provider -c 1vepskr2ms88ki76k870uflun2tjpvfs --mode auto --yes

Conclusion

This post explored how to deploy CP4I on AWS ROSA. We also demonstrated how customers can take full advantage of managed OpenShift service, focusing on further modernizing application stacks by using AWS managed services (like ROSA) for their application deployments.

If you are interested in learning more about ROSA, take part in the AWS ROSA Immersion Workshop.

Check out the blog on Running IBM MQ on AWS using High-performance Amazon FSx for NetApp ONTAP to learn how to use Amazon FSx for NetApp ONTAP for distributed storage and high availability with IBM MQ.

For more information and getting started with IBM Cloud Pak deployments, visit the AWS Marketplace for new offerings.

Further reading

AWS Week in Review – October 3, 2022

Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-week-in-review-october-3-2022/

This post is part of our Week in Review series. Check back each week for a quick roundup of interesting news and announcements from AWS!

A new week and a new month just started. Curious which were the most significant AWS news from the previous seven days? I got you covered with this post.

Last Week’s Launches
Here are the launches that got my attention last week:

Amazon File Cache – A high performance cache on AWS that accelerates and simplifies demanding cloud bursting and hybrid workflows by giving access to files using a fast and familiar POSIX interface, no matter if the original files live on premises on any file system that can be accessed through NFS v3 or on S3.

Amazon Data Lifecycle Manager – You can now automatically archive Amazon EBS snapshots to save up to 75 percent on storage costs for those EBS snapshots that you intend to retain for more than 90 days and rarely access.

AWS App Runner – You can now build and run web applications and APIs from source code using the new Node.js 16 managed runtime.

AWS Copilot – The CLI for containerized apps adds IAM permission boundaries, support for FIFO SNS/SQS for the Copilot worker-service pattern, and using Amazon CloudFront for low-latency content delivery and fast TLS-termination for public load-balanced web services.

Bottlerocket – The Linux-based operating system purpose-built to run container workloads is now supported by Amazon Inspector. Amazon Inspector can now recommend an update of Bottlerocket if it finds a vulnerability.

Amazon SageMaker Canvas – Now supports mathematical functions and operators for richer data exploration and to understand the relationships between variables in your data.

AWS Compute Optimizer – Now provides cost and performance optimization recommendations for 37 new EC2 instance types, including bare metal instances (m6g.metal) and compute optimized instances (c7g.2xlarge, hpc6a.48xlarge), and new memory metrics for Windows instances.

AWS Budgets – Use a simplified 1-click workflow for common budgeting scenarios with step-by-step tutorials on how to use each template.

Amazon Connect – Now provides an updated flow designer UI that makes it easier and faster to build personalized and automated end-customer experiences, as well as a queue dashboard to view and compare real-time queue performance through time series graphs.

Amazon WorkSpaces – You can now provision Ubuntu desktops and use virtual desktops for new categories of workloads, such as for your developers, engineers, and data scientists.

Amazon WorkSpaces Core – A fully managed infrastructure-only solution for third-party Virtual Desktop Infrastructure (VDI) management software that simplifies VDI migration and combines your current VDI software with the security and reliability of AWS. Read more about it in this Desktop and Application Streaming blog post.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Other AWS News
A few more blog posts you might have missed:

Introducing new language extensions in AWS CloudFormation – In this Cloud Operations & Migrations blog post, we introduce the new language transform that enhances CloudFormation core language with intrinsic functions that simplify handling JSON strings (Fn::ToJsonString), array lengths (Fn::Length), and update and deletion policies.

Building a GraphQL API with Java and AWS Lambda – This blog shows different options for resolving GraphQL queries using serverless technologies on AWS.

For AWS open-source news and updates, here’s the latest newsletter curated by Ricardo to bring you the most recent updates on open-source projects, posts, events, and more.

Upcoming AWS Events
As usual, there are many opportunities to meet:

AWS Summits– Connect, collaborate, and learn about AWS at these free in-person events: Bogotá (October 4), and Singapore (October 6).

AWS Community DaysAWS Community Day events are community-led conferences to share and learn together. Join us in Amersfoort, Netherlands (on October 3, today), Warsaw, Poland (October 14), and Dresden, Germany (October 19).

That’s all from me for this week. Come back next Monday for another Week in Review!

Danilo

A Decade of Ever-Increasing Provisioned IOPS for Amazon EBS

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/a-decade-of-ever-increasing-provisioned-iops-for-amazon-ebs/

Progress is often best appreciated in retrospect. It is often the case that a steady stream of incremental improvements over a long period of time ultimately adds up to a significant level of change. Today, ten years after we first launched the Provisioned IOPS feature for Amazon Elastic Block Store (EBS), I strongly believe that to be the case.

All About the IOPS
Let’s start with a quick review of IOPS, which is short for Input/Output Operations per Second. This is a number which is commonly used to characterize the performance of a storage device, and higher numbers mean better performance. In many cases, applications that generate high IOPS values will use threads, asynchronous I/O operations, and/or other forms of parallelism.

The Road to Provisioned IOPS
When we launched Amazon Elastic Compute Cloud (Amazon EC2) back in 2006 (Amazon EC2 Beta), the m1.small instances had a now-paltry 160 GiB of local disk storage. This storage had the same lifetime as the instance, and disappeared if the instance crashed or was terminated. In the run-up to the beta, potential customers told us that they could build applications even without persistent storage. During the two years between the EC2 beta and the 2008 launch of Amazon EBS, those customers were able to gain valuable experience with EC2 and to deploy powerful, scalable applications. As a reference point, these early volumes were able to deliver an average of about 100 IOPS, with bursting beyond that on a best-effort basis.

Evolution of Provisioned IOPS
As our early customers gained experience with EC2 and EBS, they asked us for more I/O performance and more flexibility. In my 2012 post (Fast Forward – Provisioned IOPS for EBS Volumes), I first told you about the then-new Provisioned IOPS (PIOPS) volumes and also introduced the concept of EBS-Optimized instances. These new volumes found a ready audience and enabled even more types of applications.

Over the years, as our customer base has become increasingly diverse, we have added new features and volume types to EBS, while also pushing forward on performance, durability, and availability. Here’s a family tree to help put some of this into context:

Today, EBS handles trillions of input/output operations daily, and supports seven distinct volume types each with a specific set of performance characteristics, maximum volume sizes, use cases, and prices. From that 2012 starting point where a single PIOPS volume could deliver up to 1000 IOPS, today’s high-end io2 Block Express volumes can deliver up to 256,000 IOPS.

Inside io2 Block Express
Let’s dive in a bit and take a closer look at io2 Block Express. These volumes make use of multiple Nitro System components including AWS Nitro SSD storage and the Nitro Card for EBS. The io2 Block Express volumes can be as large as 64 TiB, and can deliver up to 256,000 IOPS with 99.999% durability and up to 4,000 MiB/s of throughput. This performance makes them suitable for the most demanding mission-critical workloads, those that require sustained high performance and sub-millisecond latency. On the network side, the io2 Block Express volumes make use of a Scalable Reliable Datagram (SRD) protocol that is designed to deliver consistent high performance on complex, multipath networks (read A Cloud-Optimized Transport Protocol for Elastic and Scalable HPC to learn a lot more). You can use these volumes with X2idn, X2iedn, R5b, and C7g instances today, with support for additional instance types in the works.

Your Turn
Here are some resources to help you to learn more about EBS and Provisioned IOPS:

I can’t wait to see what the second decade holds for EBS and Provisioned IOPS!

Jeff;

Welcome to AWS Storage Day 2022

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/welcome-to-aws-storage-day-2022/

We are on the fourth year of our annual AWS Storage Day! Do you remember our first Storage Day 2019 and the subsequent Storage Day 2020? I watched Storage Day 2021, which was streamed live from downtown Seattle. We continue to hear from our customers about how powerful the Storage Day announcements and educational sessions were. With this year’s lineup, we aim to share our insights on how to protect your data and put it to work. The free Storage Day 2022 virtual event is happening now on the AWS Twitch channel. Tune in to hear from experts about new announcements, leadership insights, and educational content related to the broad portfolio of AWS Storage services.

Our customers are looking to reduce and optimize storage costs, while building the cloud storage skills they need for themselves and for their organizations. Furthermore, our customers want to protect their data for resiliency and put their data to work. In this blog post, you will find our insights and announcements that address all these needs and more.

Let’s get into it…

Protect Your Data
Data protection has become an operational model to deliver the resiliency of applications and the data they rely on. Organizations use the National Institute of Standards and Technology (NIST) cybersecurity framework and its Identify->Protect->Detect->Respond->Recover process to approach data protection overall. It’s necessary to consider data resiliency and recovery upfront in the Identify and Protect functions, so there is a plan in place for the later Respond and Recover functions.

AWS is making data resiliency, including malware-type recovery, table stakes for our customers. Many of our customers use Amazon Elastic Block Store (Amazon EBS) for mission-critical applications. If you already use Amazon EBS and you regularly back up EBS volumes using EBS multi-volume snapshots, I have an announcement that you will find very exciting.

Amazon EBS
Amazon EBS scales fast for the most demanding, high-performance workloads, and this is why our customers trust Amazon EBS for critical applications such as SAP, Oracle, and Microsoft. Currently, Amazon EBS enables you to back up volumes at any time using EBS Snapshots. Snapshots retain the data from all completed I/O operations, allowing you to restore the volume to its exact state at the moment before backup.

Many of our customers use snapshots in their backup and disaster recovery plans. A common use case for snapshots is to create a backup of a critical workload such as a large database or file system. You can choose to create snapshots of each EBS volume individually or choose to create multi-volume snapshots of the EBS volumes attached to a single Amazon Elastic Compute Cloud (EC2) instance. Our customers love the simplicity and peace of mind that comes with regularly backing up EBS volumes attached to a single EC2 instance using EBS multi-volume snapshots, and today we’re announcing a new feature—crash consistent snapshots for a subset of EBS volumes.

Previously, when you wanted to create multi-volume snapshots of EBS volumes attached to a single Amazon EC2 instance, if you only wanted to include some—but not all—attached EBS volumes, you had to make multiple API calls to keep only the snapshots you wanted. Now, you can choose specific volumes you want to exclude in the create-snapshots process using a single API call or by using the Amazon EC2 console, resulting in significant cost savings. Crash consistent snapshots for a subset of EBS volumes is also supported by Amazon Data Lifecycle Manager policies to automate the lifecycle of your multi-volume snapshots.

This feature is now available to you at no additional cost. To learn more, please visit the EBS Snapshots user guide.

Put Your Data to Work
We give you controls and tools to get the greatest value from your data—at an organizational level down to the individual data worker and scientist. Decisions you make today will have a long-lasting impact on your ability to put your data to work. Consider your own pace of innovation and make sure you have a cloud provider that will be there for you no matter what the future brings. AWS Storage provides the best cloud for your traditional and modern applications. We support data lakes in AWS Storage, analytics, machine learning (ML), and streaming on top of that data, and we also make cloud benefits available at the edge.

Amazon File Cache (Coming Soon)
Today we are also announcing Amazon File Cache, an upcoming new service on AWS that accelerates and simplifies hybrid cloud workloads. Amazon File Cache provides a high-speed cache on AWS that makes it easier for you to process file data, regardless of where the data is stored. Amazon File Cache serves as a temporary, high-performance storage location for your data stored in on-premises file servers or in file systems or object stores in AWS.

This new service enables you to make dispersed data sets available to file-based applications on AWS with a unified view and at high speeds with sub-millisecond latencies and up to hundreds of GB/s of throughput. Amazon File Cache is designed to enable a wide variety of cloud bursting workloads and hybrid workflows, ranging from media rendering and transcoding, to electronic design automation (EDA), to big data analytics.

Amazon File Cache will be generally available later this year. If you are interested in learning more about this service, please sign up for more information.

AWS Transfer Family
During Storage Day 2020, we announced that customers could deploy AWS Transfer Family server endpoints in Amazon Virtual Private Clouds (Amazon VPCs). AWS Transfer Family helps our customers easily manage and share data with simple, secure, and scalable file transfers. With Transfer Family, you can seamlessly migrate, automate, and monitor your file transfer workflows into and out of Amazon S3 and Amazon Elastic File System (Amazon EFS) using the SFTP, FTPS, and FTP protocols. Exchanged data is natively accessible in AWS for processing, analysis, and machine learning, as well as for integrations with business applications running on AWS.

On July 26th of this year, Transfer Family launched support for the Applicability Statement 2 (AS2) protocol. Customers across verticals such as healthcare and life sciences, retail, financial services, and insurance that rely on AS2 for exchanging business-critical data can now use AWS Transfer Family’s highly available, scalable, and globally available AS2 endpoints to more cost-effectively and securely exchange transactional data with their trading partners.

With a focus on helping you work with partners of your choice, we are excited to announce the AWS Transfer Family Delivery Program as part of the AWS Partner Network (APN) Service Delivery Program (SDP). Partners that deliver cloud-native Managed File Transfer (MFT) and business-to-business (B2B) file exchange solutions using AWS Transfer Family are welcome to join the program. Partners in this program meet a high bar, with deep technical knowledge, experience, and proven success in delivering Transfer Family solutions to our customers.

Five New AWS Storage Learning Badges
Earlier I talked about how our customers are looking to add the cloud storage skills they need for themselves and for their organizations. Currently, storage administrators and practitioners don’t have an easy way of externally demonstrating their AWS storage knowledge and skills. Organizations seeking skilled talent also lack an easy way of validating these skills for prospective employees.

In February 2022, we announced digital badges aligned to Learning Plans for Block Storage and Object Storage on AWS Skill Builder. Today, we’re announcing five additional storage learning badges. Three of these digital badges align to the Skill Builder Learning Plans in English for File, Data Protection & Disaster Recovery (DPDR), and Data Migration. Two of these badges—Core and Technologist—are tiered badges that are awarded to individuals who earn a series of Learning Plan-related badges in the following progression:

Image showing badge progression. To get the Storage Core badge users must first get Block, File, and Object badges. To get the Storage Technologist Badge users must first get the Core, Data Protection & Disaster Recovery, and Data Migration badges.

To learn more, please visit the AWS Learning Badges page.

Well, That’s It!
As I’m sure you’ve picked up on the pattern already, today’s announcements focused on continuous innovation and AWS’s ongoing commitment to providing the cloud storage training that your teams are looking for. Best of all, this AWS training is free. These announcements also focused on simplifying your data migration to the cloud, protecting your data, putting your data to work, and cost-optimization.

Now Join Us Online
Register for free and join us for the AWS Storage Day 2022 virtual event on the AWS channel on Twitch. The event will be live from 9:00 AM Pacific Time (12:00 PM Eastern Time) on August 10. All sessions will be available on demand approximately 2 days after Storage Day.

We look forward to seeing you on Twitch!

– Veliswa x

Amazon Prime Day 2022 – AWS for the Win!

Post Syndicated from Jeff Barr original https://aws.amazon.com/blogs/aws/amazon-prime-day-2022-aws-for-the-win/

As part of my annual tradition to tell you about how AWS makes Prime Day possible, I am happy to be able to share some chart-topping metrics (check out my 2016, 2017, 2019, 2020, and 2021 posts for a look back).

My purchases this year included a first aid kit, some wood brown filament for my 3D printer, and a non-stick frying pan! According to our official news release, Prime members worldwide purchased more than 100,000 items per minute during Prime Day, with best-selling categories including Amazon Devices, Consumer Electronics, and Home.

Powered by AWS
As always, AWS played a critical role in making Prime Day a success. A multitude of two-pizza teams worked together to make sure that every part of our infrastructure was scaled, tested, and ready to serve our customers. Here are a few examples:

Amazon Aurora – On Prime Day, 5,326 database instances running the PostgreSQL-compatible and MySQL-compatible editions of Amazon Aurora processed 288 billion transactions, stored 1,849 terabytes of data, and transferred 749 terabytes of data.

Amazon EC2 – For Prime Day 2022, Amazon increased the total number of normalized instances (an internal measure of compute power) on Amazon Elastic Compute Cloud (Amazon EC2) by 12%. This resulted in an overall server equivalent footprint that was only 7% larger than that of Cyber Monday 2021 due to the increased adoption of AWS Graviton2 processors.

Amazon EBS – For Prime Day, the Amazon team added 152 petabytes of EBS storage. The resulting fleet handled 11.4 trillion requests per day and transferred 532 petabytes of data per day. Interestingly enough, due to increased efficiency of some of the internal Amazon services used to run Prime Day, Amazon actually used about 4% less EBS storage and transferred 13% less data than it did during Prime Day last year. Here’s a graph that shows the increase in data transfer during Prime Day:

Amazon SES – In order to keep Prime Day shoppers aware of the deals and to deliver order confirmations, Amazon Simple Email Service (SES) peaked at 33,000 Prime Day email messages per second.

Amazon SQS – During Prime Day, Amazon Simple Queue Service (SQS) set a new traffic record by processing 70.5 million messages per second at peak:

Amazon DynamoDB – DynamoDB powers multiple high-traffic Amazon properties and systems including Alexa, the Amazon.com sites, and all Amazon fulfillment centers. Over the course of Prime Day, these sources made trillions of calls to the DynamoDB API. DynamoDB maintained high availability while delivering single-digit millisecond responses and peaking at 105.2 million requests per second.

Amazon SageMaker – The Amazon Robotics Pick Time Estimator, which uses Amazon SageMaker to train a machine learning model to predict the amount of time future pick operations will take, processed more than 100 million transactions during Prime Day 2022.

Package Planning – In North America, and on the highest traffic Prime 2022 day, package-planning systems performed 60 million AWS Lambda invocations, processed 17 terabytes of compressed data in Amazon Simple Storage Service (Amazon S3), stored 64 million items across Amazon DynamoDB and Amazon ElastiCache, served 200 million events over Amazon Kinesis, and handled 50 million Amazon Simple Queue Service events.

Prepare to Scale
Every year I reiterate the same message: rigorous preparation is key to the success of Prime Day and our other large-scale events. If you are preparing for a similar chart-topping event of your own, I strongly recommend that you take advantage of AWS Infrastructure Event Management (IEM). As part of an IEM engagement, my colleagues will provide you with architectural and operational guidance that will help you to execute your event with confidence!

Jeff;

Using AWS Backup and Oracle RMAN for backup/restore of Oracle databases on Amazon EC2: Part 1

Post Syndicated from Jeevan Shetty original https://aws.amazon.com/blogs/architecture/using-aws-backup-and-oracle-rman-for-backup-restore-of-oracle-databases-on-amazon-ec2-part-1/

Customers running Oracle databases on Amazon Elastic Compute Cloud (Amazon EC2) often take database and schema backups using Oracle native tools, like Data Pump and Recovery Manager (RMAN), to satisfy data protection, disaster recovery (DR), and compliance requirements. A priority is to reduce backup time as the data grows exponentially and recover sooner in case of failure/disaster.

In situations where RMAN backup is used as a DR solution, using AWS Backup to backup the file system and using RMAN to backup the archive logs are an efficient method to perform Oracle database point-in-time recovery in the event of a disaster.

Sample use cases:

  1. Quickly build a copy of production database to test bug fixes or for a tuning exercise.
  2. Recover from a user error that removes data or corrupts existing data.
  3. A complete database recovery after a media failure.

There are two options to backup the archive logs using RMAN:

  1. Using Oracle Secure Backup (OSB) and an Amazon Simple Storage Service (Amazon S3) bucket as the storage for archive logs
  2. Using Amazon Elastic File System (Amazon EFS) as the storage for archive logs

This is Part 1 of this two-part series, we provide a mechanism to use AWS Backup to create a full backup of the EC2 instance, including the OS image, Oracle binaries, logs, and data files. In this post, we will use Oracle RMAN to perform archived redo log backup to an Amazon S3 bucket. Then, we demonstrate the steps to restore a database to a specific point-in-time using AWS Backup and Oracle RMAN.

Solution overview

Figure 1 demonstrates the workflow:

  1. Oracle database on Amazon EC2 configured with Oracle Secure Backup (OSB)
  2. AWS Backup service to backup EC2 instance at regular intervals.
  3. AWS Identity and Access Management (IAM) role for EC2 instance that grants permission to write archive log backups to Amazon S3
  4. S3 bucket for storing Oracle RMAN archive log backups
Figure 1. Oracle Database in Amazon EC2 using AWS Backup and S3 for backup and restore

Figure 1. Oracle Database in Amazon EC2 using AWS Backup and S3 for backup and restore

Prerequisites

For this solution, the following prerequisites are required:

  1. An AWS account
  2. Oracle database and AWS CLI in an EC2 instance
  3. Access to configure AWS Backup
  4. Acces to S3 bucket to store the RMAN archive log backup

1. Configure AWS Backup

You can choose AWS Backup to schedule daily backups of the EC2 instance. AWS Backup efficiently stores your periodic backups using backup plans. Only the first EBS snapshot performs a full copy from Amazon Elastic Block Storage (Amazon EBS) to Amazon S3. All subsequent snapshots are incremental snapshots, copying just the changed blocks from Amazon EBS to Amazon S3, thus, reducing backup duration and storage costs. Oracle supports Storage Snapshot Optimization, which takes third-party snapshots of the database without placing the database in backup mode. By default, AWS Backup now creates crash-consistent backups of Amazon EBS volumes that are attached to an EC2 instance. Customers no longer have to stop their instance or coordinate between multiple Amazon EBS volumes attached to the same EC2 instance to ensure crash-consistency of their application state.

You can create daily scheduled backup of EC2 instances. Figures 2, 3, and 4 are sample screenshots of the backup plan, associating an EC2 instance with the backup plan.

Configure backup rule using AWS Backup

Figure 2. Configure backup rule using AWS Backup

Select EC2 instance containing Oracle Database for backup

Figure 3. Select EC2 instance containing Oracle Database for backup

Summary screen showing the backup rule and resources managed by AWS Backup

Figure 4. Summary screen showing the backup rule and resources managed by AWS Backup

Oracle RMAN archive log backup

While AWS Backup is now creating a daily backup of the EC2 instance, we also want to make sure we backup the archived log files to a protected location. This will let us do point-in-time restores and restore to other recent times than just the last daily EC2 backup. Here, we provide the steps to backup archive log using RMAN to S3 bucket.

Backup/restore archive logs to/from Amazon S3 using OSB

Backing-up the Oracle archive logs is an important part of the process. In this section, we will describe how you can backup their Oracle Archive logs to Amazon S3 using OSB. Note: OSB is a separately licensed product from Oracle Corporation, so you will need to be properly licensed for OSB if you use this approach.

2. Setup S3 bucket and IAM role

Oracle Archive log backups can be scheduled using cron script to run at regular interval (for example, every 15 minutes). These backups are stored in an S3 bucket.

a. Create an S3 bucket with lifecycle policy to transition the objects to S3 Standard-Infrequent Access.
b. Attach the following policy to the IAM Role of EC2 containing Oracle database or create an IAM role (ec2access) with the following policy and attach it to the EC2 instance. Update bucket-name with the bucket created in previous step.


        {
            "Sid": "S3BucketAccess",
            "Effect": "Allow",
            "Action": [
                "s3:PutObject",
                "s3:GetObjectAcl",
                "s3:GetObject",
                "s3:ListBucket",
                "s3:DeleteObject"
            ],
            "Resource": [
                "arn:aws:s3:::bucket-name",
                "arn:aws:s3:::bucket-name/*"
            ]
        }

3. Setup OSB

After we have configured the backup of EC2 instance using AWS Backup, we setup OSB in the EC2 instance. In these steps, we show the mechanism to configure OSB.

a. Verify hardware and software prerequisites for OSB Cloud Module.
b. Login to the EC2 instance with User ID owning the Oracle Binaries.
c. Download Amazon S3 backup installer file (osbws_install.zip)
d. Create Oracle wallet directory.

mkdir $ORACLE_HOME/dbs/osbws_wallet

e. Create a file (osbws.sh) in the EC2 instance with the following commands. Update IAM role with the one created/updated in Step 2b.

java -jar osbws_install.jar —IAMRole ec2access walletDir $ORACLE_HOME/dbs/osbws_wallet -libDir $ORACLE_HOME/lib/

f. Change permission and run the file.

chmod 700 osbws.sh
./osbws.sh

Sample output: AWS credentials are valid.
Oracle Secure Backup Web Service wallet created in directory /u01/app/oracle/product/19.3.0.0/db_1/dbs/osbws_wallet.
Oracle Secure Backup Web Service initialization file /u01/app/oracle/product/19.3.0.0/db_1/dbs/osbwsoratst.ora created.
Downloading Oracle Secure Backup Web Service Software Library from file osbws_linux64.zip.
Download complete.

g. Set ORACLE_SID by executing below command:

. oraenv

h. Running the script – osbws.sh installs OSB libraries and creates a file called osbws<ORACLE_SID>.ora.
i. Add/modify below with S3 bucket(bucket-name) and region(ex:us-west-2) created in Step 2a.

OSB_WS_HOST=http://s3.us-west-2.amazonaws.com
OSB_WS_BUCKET=bucket-name
OSB_WS_LOCATION=us-west-2

4. Configure RMAN backup to S3 bucket

With OSB installed in the EC2 instance, you can backup Oracle archive logs to S3 bucket. These backups can be used to perform database point-in-time recovery in case of database crash/corruption . oratst is used as an example in below commands.

a. Configure RMAN repository. Example below uses Oracle 19c and Oracle Sid – oratst.

RMAN> configure channel device type sbt parms='SBT_LIBRARY=/u01/app/oracle/product/19.3.0.0/db_1/lib/libosbws.so,SBT_PARMS=(OSB_WS_PFILE=/u01/app/oracle/product/19.3.0.0/db_1/dbs/osbwsoratst.ora)';

b. Create a script (for example, rman_archive.sh) with below commands, and schedule using crontab (example entry: */5 * * * * rman_archive.sh) to run every 5 minutes. This will makes sure Oracle Archive logs are backed up to Amazon S3 frequently, thus ensuring an recovery point objective (RPO) of 5 minutes.

dt=`date +%Y%m%d_%H%M%S`

rman target / log=rman_arch_bkup_oratst_${dt}.log <<EOF

RUN
{
	allocate channel c1_s3 device type sbt
	parms='SBT_LIBRARY=/u01/app/oracle/product/19.3.0.0/db_1/lib/libosbws.so,SBT_PARMS=(OSB_WS_PFILE=/u01/app/oracle/product/19.3.0.0/db_1/dbs/osbwsoratst.ora)' MAXPIECESIZE 10G;

	BACKUP ARCHIVELOG ALL delete all input;
	Backup CURRENT CONTROLFILE;

release channel c1_s3;
	
}

EOF

c. Copy RMAN logs to S3 bucket. These logs contain the database identifier (DBID) that is required when we have to restore the database using Oracle RMAN.

aws s3 cp rman_arch_bkup_oratst_${dt}.log s3://bucket-name

5. Perform database point-in-time recovery

In the event of a database crash/corruption, we can use AWS Backup service and Oracle RMAN Archive log backup to recover database to a specific point-in-time.

a. Typically, you would pick the most recent recovery point completed before the time you wish to recover. Using AWS Backup, identify the recovery point ID to restore by following the steps on restoring an Amazon EC2 instance. Note: when following the steps, be sure to set the “User data” settings as described in the next bullet item.

After the EBS volumes are created from the snapshot, there is no need to wait for all of the data to transfer from Amazon S3 to your EBS volume before your attached instance can start accessing the volume. Amazon EBS snapshots implement lazy loading, so that you can begin using them right away.

b. Be sure the database does not start automatically after restoring the EC2 instance, by renaming /etc/oratab. Use the following command in “User data” section while restoring EC2 instance. After database recovery, we can rename it back to /etc/oratab.

#!/usr/bin/sh
sudo su - 
mv /etc/oratab /etc/oratab_bk

c. Login to the EC2 instance once it is up, and execute the RMAN recovery commands mentioned. Identify the DBID from RMAN logs saved in the S3 bucket. These commands use database oratst as an example:

rman target /

RMAN> startup nomount

RMAN> set dbid DBID

# Below command is to restore the controlfile from autobackup

RMAN> RUN
{
    allocate channel c1_s3 device type sbt
	parms='SBT_LIBRARY=/u01/app/oracle/product/19.3.0.0/db_1/lib/libosbws.so,SBT_PARMS=(OSB_WS_PFILE=/u01/app/oracle/product/19.3.0.0/db_1/dbs/osbwsoratst.ora)';

    RESTORE CONTROLFILE FROM AUTOBACKUP;
    alter database mount;

    release channel c1_s3;
}


#Identify the recovery point (sequence_number) by listing the backups available in catalog.

RMAN> list backup;

In Figure 5, the most recent archive log backed up is 380, so you can use this sequence number in the next set of RMAN commands.

Sample output of Oracle RMAN “list backup” command

Figure 5. Sample output of Oracle RMAN “list backup” command

RMAN> RUN
{
    allocate channel c1_s3 device type sbt
	parms='SBT_LIBRARY=/u01/app/oracle/product/19.3.0.0/db_1/lib/libosbws.so,SBT_PARMS=(OSB_WS_PFILE=/u01/app/oracle/product/19.3.0.0/db_1/dbs/osbwsoratst.ora)';

    recover database until sequence sequence_number;
    ALTER DATABASE OPEN RESETLOGS;
    release channel c1_s3;
}

d. To avoid performance issues due to lazy loading, after the database is open, run the following command to force a faster restoration of the blocks from S3 bucket to EBS volumes (this example allocates two channels and validates the entire database).

RMAN> RUN
{
  ALLOCATE CHANNEL c1 DEVICE TYPE DISK;
  ALLOCATE CHANNEL c2 DEVICE TYPE DISK;
  VALIDATE database section size 1200M;
}

e. This completes the recovery of database, and we can let the database automatically start by renaming file back to /etc/oratab.

mv /etc/oratab_bk /etc/oratab

6. Backup retention

Ensure that the AWS Backup lifecycle policy matches the Oracle Archive log backup retention. Also, follow documentation to configure Oracle backup retention and delete expired backups. This is a sample command for Oracle backup retention:

CONFIGURE BACKUP OPTIMIZATION ON;
CONFIGURE RETENTION POLICY TO RECOVERY WINDOW OF 31 DAYS; 

RMAN> RUN
{
    allocate channel c1_s3 device type sbt
	parms='SBT_LIBRARY=/u01/app/oracle/product/19.3.0.0/db_1/lib/libosbws.so,SBT_PARMS=(OSB_WS_PFILE=/u01/app/oracle/product/19.3.0.0/db_1/dbs/osbwsoratst.ora)';

            crosscheck backup;
            delete noprompt obsolete;
            delete noprompt expired backup;

    release channel c1_s3;
}

Cleanup

Follow below instructions to remove or cleanup the setup:

  1. Delete the backup plan created in Step 1.
  2. Uninstall Oracle Secure Backup from the EC2 instance.
  3. Delete/Update IAM role (ec2access) to remove access from the S3 bucket used to store archive logs.
  4. Remove the cron entry from the EC2 instance configured in Step 4b.
  5. Delete the S3 bucket that was created in Step 2a to store Oracle RMAN archive log backups.

Conclusion

In this post, we demonstrate how to use AWS Backup and Oracle RMAN Archive log backup of Oracle databases running on Amazon EC2 can restore and recover efficiently to a point-in-time, without requiring an extra-step of restoring data files. Data files are restored as part of the AWS Backup EC2 instance restoration. You can leverage this solution to facilitate restoring copies of your production database for development or testing purposes, plus recover from a user error that removes data or corrupts existing data.

To learn more about AWS Backup, refer to the AWS Backup AWS Backup Documentation.

Identification of replication bottlenecks when using AWS Application Migration Service

Post Syndicated from Tobias Reekers original https://aws.amazon.com/blogs/architecture/identification-of-replication-bottlenecks-when-using-aws-application-migration-service/

Enterprises frequently begin their journey by re-hosting (lift-and-shift) their on-premises workloads into AWS and running Amazon Elastic Compute Cloud (Amazon EC2) instances. A simpler way to re-host is by using AWS Application Migration Service (Application Migration Service), a cloud-native migration service.

To streamline and expedite migrations, automate reusable migration patterns that work for a wide range of applications. Application Migration Service is the recommended migration service to lift-and-shift your applications to AWS.

In this blog post, we explore key variables that contribute to server replication speed when using Application Migration Service. We will also look at tests you can run to identify these bottlenecks and, where appropriate, include remediation steps.

Overview of migration using Application Migration Service

Figure 1 depicts the end-to-end data replication flow from source servers to a target machine hosted on AWS. The diagram is designed to help visualize potential bottlenecks within the data flow, which are denoted by a black diamond.

Data flow when using AWS Application Migration Service (black diamonds denote potential points of contention)

Figure 1. Data flow when using AWS Application Migration Service (black diamonds denote potential points of contention)

Baseline testing

To determine a baseline replication speed, we recommend performing a control test between your target AWS Region and the nearest Region to your source workloads. For example, if your source workloads are in a data center in Rome and your target Region is Paris, run a test between eu-south-1 (Milan) and eu-west-3 (Paris). This will give a theoretical upper bandwidth limit, as replication will occur over the AWS backbone. If the target Region is already the closest Region to your source workloads, run the test from within the same Region.

Network connectivity

There are several ways to establish connectivity between your on-premises location and AWS Region:

  1. Public internet
  2. VPN
  3. AWS Direct Connect

This section pertains to options 1 and 2. If facing replication speed issues, the first place to look is at network bandwidth. From a source machine within your internal network, run a speed test to calculate your bandwidth out to the internet; common test providers include Cloudflare, Ookla, and Google. This is your bandwidth to the internet, not to AWS.

Next, to confirm the data flow from within your data center, run a traceroute (Windows) or tracert (Linux). Identify any network hops that are unusual or potentially throttling bandwidth (due to hardware limitations or configuration).

To measure the maximum bandwidth between your data center and the AWS subnet that is being used for data replication, while accounting for Security Sockets Layer (SSL) encapsulation, use the CloudEndure SSL bandwidth tool (refer to Figure 1).

Source storage I/O

The next area to look for replication bottlenecks is source storage. The underlying storage for servers can be a point of contention. If the storage is maxing-out its read speeds, this will impact the data-replication rate. If your storage I/O is heavily utilized, it can impact block replication by Application Migration Service. In order to measure storage speeds, you can use the following tools:

  • Windows: WinSat (or other third-party tooling, like AS SSD Benchmark)
  • Linux: hdparm

We suggest reducing read/write operations on your source storage when starting your migration using Application Migration Service.

Application Migration Service EC2 replication instance size

The size of the EC2 replication server instance can also have an impact on the replication speed. Although it is recommended to keep the default instance size (t3.small), it can be increased if there are business requirements, like to speed up the initial data sync. Note: using a larger instance can lead to increased compute costs.

-508 (1)

Common replication instance changes include:

  • Servers with <26 disks: change the instance type to m5.large. Increase the instance type to m5.xlarge or higher, as needed.
  • Servers with <26 disks (or servers in AWS Regions that do not support m5 instance types): change the instance type to m4.large. Increase to m4.xlarge or higher, as needed.

Note: Changing the replication server instance type will not affect data replication. Data replication will automatically pick up where it left off, using the new instance type you selected.

Application Migration Service Elastic Block Store replication volume

You can customize the Amazon Elastic Block Store (Amazon EBS) volume type used by each disk within each source server in that source server’s settings (change staging disk type).

By default, disks <500GiB use Magnetic HDD volumes. AWS best practice suggests not change the default Amazon EBS volume type, unless there is a business need for doing so. However, as we aim to speed up the replication, we actively change the default EBS volume type.

There are two options to choose from:

  1. The lower cost, Throughput Optimized HDD (st1) option utilizes slower, less expensive disks.

-508 (2)

    • Consider this option if you(r):
      • Want to keep costs low
      • Large disks do not change frequently
      • Are not concerned with how long the initial sync process will take
  1. The faster, General Purpose SSD (gp2) option utilizes faster, but more expensive disks.

-508 (3)

    • Consider this option if you(r):
      • Source server has disks with a high write rate, or if you need faster performance in general
      • Want to speed up the initial sync process
      • Are willing to pay more for speed

Source server CPU

The Application Migration Service agent that is installed on the source machine for data replication uses a single core in most cases (agent threads can be scheduled to multiple cores). If core utilization reaches a maximum, this can be a limitation for replication speed. In order to check the core utilization:

  • Windows: Launch the Task Manger application within Windows, and click on the “CPU” tab. Right click on the CPU graph (this is currently showing an average of cores) > select “Change graph to” > “Logical processors”. This will show individual cores and their current utilization (Figure 2).
Logical processor CPU utilization

Figure 2. Logical processor CPU utilization

Linux: Install htop and run from the terminal. The htop command will display the Application Migration Service/CE process and indicate the CPU and memory utilization percentage (this is of the entire machine). You can check the CPU bars to determine if a CPU is being maxed-out (Figure 3).

AWS Application Migration Service/CE process to assess CPU utilization

Figure 3. AWS Application Migration Service/CE process to assess CPU utilization

Conclusion

In this post, we explored several key variables that contribute to server replication speed when using Application Migration Service. We encourage you to explore these key areas during your migration to determine if your replication speed can be optimized.

Related information

Multi-Region Migration using AWS Application Migration Service

Post Syndicated from Shreya Pathak original https://aws.amazon.com/blogs/architecture/multi-region-migration-using-aws-application-migration-service/

AWS customers are in various stages of their cloud journey. Frequently, enterprises begin that journey by rehosting (lift-and-shift migrating) their on-premises workloads into AWS, and running Amazon Elastic Compute Cloud (Amazon EC2) instances. You can rehost using AWS Application Migration Service (MGN), a cloud-native migration tool.

You may need to relocate instances and workloads to a Region that is closer in proximity to one of your offices or data centers. Or you may have a resilience requirement to balance your workloads across multiple Regions. This rehosting migration pattern with AWS MGN can also be used to migrate Amazon EC2-hosted workloads from one AWS Region to another.

In this blog post, we will show you how to configure AWS MGN for migrating your workloads from one AWS Region to another.

Overview of AWS MGN migration

AWS MGN, an AWS native service, minimizes time-intensive, error-prone, manual processes by automatically converting your source servers from physical, virtual, or cloud infrastructure to run natively on AWS. It reduces overall migration costs, such as investment in multiple migration solutions, specialized cloud development, or application-specific skills. With AWS MGN, you can migrate your applications from physical infrastructure, VMware vSphere, Microsoft Hyper-V, Amazon EC2, and Amazon Virtual Private Cloud (Amazon VPC) to AWS.

To migrate to AWS, install the AWS MGN Replication Agent on your source servers and define replication settings in the AWS MGN console, shown in Figure 1. Replication servers receive data from an agent running on source servers, and write this data to the Amazon Elastic Block Store (EBS) volumes. Your replicated data is compressed and encrypted in transit and at rest using EBS encryption.

AWS MGN keeps your source servers up to date on AWS using nearly continuous, block-level data replication. It uses your defined launch settings to launch instances when you conduct non-disruptive tests or perform a cutover. After confirming that your launched instances are operating properly on AWS, you can decommission your source servers.

Figure 1. MGN service architecture

Figure 1. MGN service architecture

Steps for migration with AWS MGN

This tutorial assumes that you already have your source AWS Region set up with Amazon EC2-hosted workloads running and a target AWS Region defined.

Migrating Amazon EC2 workload across AWS Regions include the following steps:

  1. Create the Replication Settings template. These settings are used to create and manage your staging area subnet with lightweight Amazon EC2 instances. These instances act as replication servers used to replicate data between your source servers and AWS.
  2. Install the AWS Replication Agent on your source instances to add them to the AWS MGN console.
  3. Configure the launch settings for each source server. These are a set of instructions that determine how a Test or Cutover instance will be launched for each source server on AWS.
  4. Initiate the test/cutover to the target Region.

Prerequisites

Following are the prerequisites:

Setting up AWS MGN for multi-Region migration

This section will guide you through AWS MGN configuration setup for multi-Region migration.

Log into your AWS account, select the target AWS Region, and complete the prerequisites. Then you are ready to configure AWS MGN:

1.      Choose Get started on the AWS MGN landing page.

2.      Create the Replication Settings template (see Figure 2):

  • Select Staging area subnet for Replication Server
  • Choose Replication Server instance type (By default, AWS MGN uses t3.small instance type)
  • Choose default or custom Amazon EBS encryption
  • Enable ‘Always use the Application Migration Service security group’
  • Add custom Replication resources tags
  • Select Create Template button
Figure 2. Replication Settings template creation

Figure 2. Replication Settings template creation

3.      Add source servers to AWS MGN:

  • Select Add Servers following Source Servers (AWS MGN > Source Servers)
  • Enter OS, Replication Preferences, IAM Access Key and Secret Access Key ID of the IAM user created following Prerequisites. This does not expose your Secret Access Key ID in any request
  • Copy the installation command and run on your source server for agent installation

After successful agent installation, the source server is listed on the Source Servers page. Data replication begins after completion of the Initial Sync steps.

4.      Monitor the Initial Sync status (shown in Figure 3):

  •  Source server name > Migration Dashboard > Data Replication Status
    (Refer to the Source Servers page documentation for more details)
  • After 100% initial data replication confirm:
    • Migration Lifecycle = Ready for testing
    • Next step = Launch test instance
Figure 3. Monitoring initial replication status

Figure 3. Monitoring initial replication status

5.      Configure Launch Settings for each server:

  • Source servers page > Select source server
  • Navigate to the Launch settings tab (see Figure 4.) For this tutorial we won’t adjust the General launch settings. We will modify the EC2 Launch Template instead
  • Click on EC2 Launch Template > About modifying EC2 Launch Templates > Modify
Figure 4. Modifying EC2 Launch Template

Figure 4. Modifying EC2 Launch Template

6.      Provide values for Launch Template:

  • AMI: Recents tab > Don’t include in launch template
  • Instance Type: Can be kept same as source server or changed as per expected workload
  • Key pair (login): Create new or use existing if already created in the Target AWS Region
  • Network Settings > Subnet: Subnet for launching Test instance
  • Advanced network configuration:
    • Security Groups: For access to the test and final cutover instances
    • Configure Storage: Size – Do not change or edit this field
    • Volume type: Select any volume type (io1 is default)
  • Review details and click Create Template Version under the Summary section on right side of the console

7.      Every time you modify the Launch template, a new version is created. Set the launch template that you want to use with MGN as the default (shown in Figure 5):

  • Navigate to Amazon EC2 dashboard > Launch Templates page
  • Select the Launch template ID
  • Open the Actions menu and choose Set default version and select the latest Launch template created
Figure 5. Setting up your Launch template as the default

Figure 5. Setting up your Launch template as the default

8.      Launch a test instance and perform a Test prior to Cutover to identify potential problems and solve them before the actual Cutover takes place:

  • Go to the Source Servers page (see Figure 6)
  • Select source server > Open Test and Cutover menu
  • Under Testing, choose Launch test instances
  • Launch test instances for X servers > Launch
  • Choose View job details on the ‘Launch Job Created’ dialog box to view the specific Job details for the test launch in the Launch History tab
Figure 6. Launching test instances

Figure 6. Launching test instances

9.      Validate launch of test instance (shown in Figure 7) by confirming:

  • Alerts column = Launched
  • Migration lifecycle column = Test in progress
  • Next step column = Complete testing and mark as ‘Ready for cutover’
Figure 7. Validating launch of test instances

Figure 7. Validating launch of test instances

10.  SSH/ RDP into Test instance (view from EC2 console) and validate connectivity. Perform acceptance tests for your application as required. Revert the test if you encounter any issues.

11.  Terminate Test instances after successful testing:

  • Go to Source servers page
  • Select source server > Open Test and Cutover menu
  • Under Testing, choose Mark as “Ready for cutover”
  • Mark X servers as “Ready for cutover” > Yes, terminate launched instances (recommended) > Continue

12.  Validate the status of termination job and cutover readiness:

  • Migration Lifecycle = Ready for cutover
  • Next step = Launch cutover instance

13.  Perform the final cutover at a set date and time:

  • Go to Source servers page (see Figure 8)
  • Select source server > Open Test and Cutover menu
  • Under Cutover, choose Launch cutover instances
  • Launch cutover instances for X > Launch
Figure 8. Performing final Cutover by launching Cutover instances

Figure 8. Performing final Cutover by launching Cutover instances

14.  Monitor the indicators to validate the success of the launch of your Cutover instance (shown in Figure 9):

  • Alerts column = Launched
  • Migration lifecycle column = Cutover in progress
  • Data replication status = Healthy
  • Next step column = Finalize cutover
Figure 9. Indicators for successful launch of Cutover instances

Figure 9. Indicators for successful launch of Cutover instances

15.  Test Cutover Instance:

  • Navigate to Amazon EC2 console > Instances (running)
  • Select Cutover instance
  • SSH/ RDP into your Cutover instance to confirm that it functions correctly
  • Validate connectivity and perform acceptance tests for your application
  • Revert Cutover if any issues

16.  Finalize the cutover after successful validation:

  • Navigate to AWS MGN console > Source servers page
  • Select source server > Open Test and Cutover menu
  • Under Cutover, choose Finalize Cutover
  • Finalize cutover for X servers > Finalize

17.  At this point, if your cutover is successful:

  • Migration lifecycle column = Cutover complete,
  • Data replication status column = Disconnected
  • Next step column = Mark as archived

The cutover is now complete and that the migration has been performed successfully. Data replication has also stopped and all replicated data will now be discarded.

Cleaning up

Archive your source servers that have launched Cutover instances to clean up your Source Servers page-

  • Navigate to Source Servers page (see Figure 10)
  • Select source server > Open Actions
  • Choose Mark as archived
  • Archive X server > Archive
Figure 10. Mark source servers as archived that are cutover

Figure 10. Mark source servers as archived that are cutover

Conclusion

In this post, we demonstrated how AWS MGN simplifies, expedites, and reduces the cost of migrating Amazon EC2-hosted workloads from one AWS Region to another. It integrates with AWS Migration Hub, enabling you to organize your servers into applications. You can track the progress of all your MGN at the server and app level, even as you move servers into multiple AWS Regions. Choose a Migration Hub Home Region for MGN to work with the Migration Hub.

Here are the AWS MGN supported AWS Regions. If your preferred AWS Region isn’t currently supported or you cannot install agents on your source servers, consider using CloudEndure Migration or AWS Server Migration Service respectively. CloudEndure Migration will be discontinued in all AWS Regions on December 30, 2022. Refer to CloudEndure Migration EOL for more information.

Note: Use of AWS MGN is free for 90 days but you will incur charges for any AWS infrastructure that is provisioned during migration and after cutover. For more information, refer to the pricing page.

Thanks for reading this blog post! If you have any comments or questions, feel free to put them in the comments section.

Creating a Multi-Region Application with AWS Services – Part 1, Compute and Security

Post Syndicated from Joe Chapman original https://aws.amazon.com/blogs/architecture/creating-a-multi-region-application-with-aws-services-part-1-compute-and-security/

Building a multi-Region application requires lots of preparation and work. Many AWS services have features to help you build and manage a multi-Region architecture, but identifying those capabilities across 200+ services can be overwhelming.

In this 3-part blog series, we’ll explore AWS services with features to assist you in building multi-Region applications. In Part 1, we’ll build a foundation with AWS security, networking, and compute services. In Part 2, we’ll add in data and replication strategies. Finally, in Part 3, we’ll look at the application and management layers.

Considerations before getting started

AWS Regions are built with multiple isolated and physically separate Availability Zones (AZs). This approach allows you to create highly available Well-Architected workloads that span AZs to achieve greater fault tolerance. There are three general reasons that you may need to expand beyond a single Region:
  • Expansion to a global audience as an application grows and its user base becomes more geographically dispersed, there can be a need to reduce latencies for different parts of the world.
  • Reducing Recovery Point Objectives (RPO) and Recovery Time Objectives (RTO) as part of disaster recovery (DR) plan.
  • Local laws and regulations may have strict data residency and privacy requirements that must be followed.

Ensuring security, identity, and compliance

Creating a security foundation starts with proper authentication, authorization, and accounting to implement the principle of least privilege. AWS Identity and Access Management (IAM) operates in a global context by default. With IAM, you specify who can access which AWS resources and under what conditions. For workloads that use directory services, the AWS Directory Service for Microsoft Active Directory Enterprise Edition can be set up to automatically replicate directory data across Regions. This allows applications to reduce lookup latencies by using the closest directory and creates durability by spanning multiple Regions.

Applications that need to securely store, rotate, and audit secrets, such as database passwords, should use AWS Secrets Manager. It encrypts secrets with AWS Key Management Service (AWS KMS) keys and can replicate secrets to secondary Regions to ensure applications are able to obtain a secret in the closest Region.

Encrypt everything all the time

AWS KMS can be used to encrypt data at rest, and is used extensively for encryption across AWS services. By default, keys are confined to a single Region. AWS KMS multi-Region keys can be created to replicate keys to a second Region, which eliminates the need to decrypt and re-encrypt data with a different key in each Region.

AWS CloudTrail logs user activity and API usage. Logs are created in each Region, but they can be centralized from multiple Regions and multiple accounts into a single Amazon Simple Storage Service (Amazon S3) bucket. As a best practice, these logs should be aggregated to an account that is only accessible to required security personnel to prevent misuse.

As your application expands to new Regions, AWS Security Hub can aggregate and link findings to a single Region to create a centralized view across accounts and Regions. These findings are continuously synced between Regions to keep you updated on global findings.

We put these features together in Figure 1.

Multi-Region security, identity, and compliance services

Figure 1. Multi-Region security, identity, and compliance services

Building a global network

For resources launched into virtual networks in different Regions, Amazon Virtual Private Cloud (Amazon VPC) allows private routing between Regions and accounts with VPC peering. These resources can communicate using private IP addresses and do not require an internet gateway, VPN, or separate network appliances. This works well for smaller networks that only require a few peering connections. However, as the number of peered connections increases, the mesh of peered connections can become difficult to manage and troubleshoot.

AWS Transit Gateway can help reduce these difficulties by creating a central transitive hub to act as a cloud router. A Transit Gateway’s routing capabilities can expand to additional Regions with Transit Gateway inter-Region peering to create a globally distributed private network.

Building a reliable, cost-effective way to route users to distributed Internet applications requires highly available and scalable Domain Name System (DNS) records. Amazon Route 53 does exactly that.

Route 53 routing policies can route traffic to a record with the lowest latency, or automatically fail over a record. If a larger failure occurs, the Route 53 Application Recovery Controller can simplify the monitoring and failover process for application failures across Regions, AZs, and on-premises.

Amazon CloudFront’s content delivery network is truly global, built across 300+ points of presence (PoP) spread throughout the world. Applications that have multiple possible origins, such as across Regions, can use CloudFront origin failover to automatically fail over the origin. CloudFront’s capabilities expand beyond serving content, with the ability to run compute at the edge. CloudFront functions make it easy to run lightweight JavaScript functions, and AWS Lambda@Edge makes it easy to run Node.js and Python functions across these 300+ PoPs.

AWS Global Accelerator uses the AWS global network infrastructure to provide two static anycast IPs for your application. It automatically routes traffic to the closest Region deployment, and if a failure is detected it will automatically redirect traffic to a healthy endpoint within seconds.

Figure 2 brings these features together to create a global network across two Regions.

AWS VPC connectivity and content delivery

Figure 2. AWS VPC connectivity and content delivery

Building the compute layer

An Amazon Elastic Compute Cloud (Amazon EC2) instance is based on an Amazon Machine Image (AMI). An AMI specifies instance configurations such as the instance’s storage, launch permissions, and device mappings. When a new standard image needs to be created, EC2 Image Builder can be used to streamline copying AMIs to selected Regions.

Although EC2 instances and their associated Amazon Elastic Block Store (Amazon EBS) volumes live in a single AZ, Amazon Data Lifecycle Manager can automate the process of taking and copying EBS snapshots across Regions. This can enhance DR strategies by providing a relatively easy cold backup-and-restore option for EBS volumes.

As an architecture expands into multiple Regions, it can become difficult to track where instances are provisioned. Amazon EC2 Global View helps solve this by providing a centralized dashboard to see Amazon EC2 resources such as instances, VPCs, subnets, security groups, and volumes in all active Regions.

Microservice-based applications that use containers benefit from quicker start-up times. Amazon Elastic Container Registry (Amazon ECR) can help ensure this happens consistently across Regions with private image replication at the registry level. An ECR private registry can be configured for either cross-Region or cross-account replication to ensure your images are ready in secondary Regions when needed.

We bring these compute layer features together in Figure 3.

AMI and EBS snapshot copy across Regions

Figure 3. AMI and EBS snapshot copy across Regions

Summary

It’s important to create a solid foundation when architecting a multi-Region application. These foundations pave the way for you to move fast in a secure, reliable, and elastic way as you build out your application. In this post, we covered options across AWS security, networking, and compute services that have built-in functionality to take away some of the undifferentiated heavy lifting. We’ll cover data, application, and management services in future posts.

Ready to get started? We’ve chosen some AWS Solutions and AWS Blogs to help you!

Looking for more architecture content? AWS Architecture Center provides reference architecture diagrams, vetted architecture solutions, Well-Architected best practices, patterns, icons, and more!

New – Amazon EBS Snapshots Archive

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/new-amazon-ebs-snapshots-archive/

I am pleased to announce the availability of Amazon EBS Snapshots Archive, a new storage tier for the long-term retention of Amazon Elastic Block Store (EBS) snapshots of your EBS volumes.

In a nutshell, EBS is an easy-to-use high-performance block storage service for your Amazon Elastic Compute Cloud (Amazon EC2) instances. An EBS volume mounted to your EC2 instances lets you boot an operating system and store data for your most performance-demanding workloads. You may use EBS snapshots to create point-in-time copies of your volume data. The first snapshot of a volume contains all of the data written into that volume. Subsequent snapshots are incremental. Snapshots are stored on Amazon Simple Storage Service (Amazon S3), and they may be shared between AWS accounts and AWS Regions.

The ability to take frequent snapshots and easily restore volumes makes EBS snapshots an obvious choice for your data management strategy, alongside other backup options. The incremental nature of snapshots makes them cost-effective for daily and weekly backups that need immediate restores. However, you were telling us that business compliance and regulatory needs have meant that you needed to retain EBS snapshots for longer periods of time (months or years). For example, snapshots taken at the end of a project, or snapshots for test and development preserved for future project releases. The vast majority of these snapshots are taken and never read. For these snapshots, you are looking to lower your storage costs. Today, to benefit from lower storage costs, you may have written complex scripts involving temporary EC2 instances to restore snapshots, mount the corresponding volumes, and transfer the data to lower-cost storage tiers, such as Amazon Glacier.

EBS Snapshots Archive provides a low-cost storage tier to archive full, point-in-time copies of EBS Snapshots that you must retain for 90 days or more for regulatory and compliance reasons, or for future project releases. Now, you can easily archive and manage EBS Snapshots, thereby eliminating the need for custom scripts and third-party tools to manage these snapshots. This lets you move your rarely accessed snapshots to EBS Snapshots Archive to achieve up to 75% lower storage costs, and avoid licensing costs for third-party tools. Furthermore, you can retrieve an archived snapshot within 24-72 hours, and, once restored, use the snapshot to recover an EBS volume.

As per usual, let me show you how it works.

How to Get Started
I have a snapshot available in the US East (N. Virginia) Region, and I want to archive this snapshot for compliance reasons. I open the AWS Management Console, navigate to EC2, then to Snapshots. I select the snapshot I want to archive, and select the Actions menu. I select the Archive snapshot menu option.

EBS Snapshot Archive - create snapshot

I carefully read the confirmation message :-), and I select Archive snapshot.

EBS Snapshot Archive - create snapshot - confirmation

I may monitor the progress of the archive operation with the new Storage Tier tab at the bottom of the screen. After some time, depending on the size of the snapshot, the Tiering status becomes ✅ Archival completed.

EBS Snapshot Archive - create snapshot - archival completedArchived snapshots stay visible in the console. The new Storage tier column indicates the tier used for storage (Standard or Archive).

How do I Restore a Volume?
Restoring a volume from EBS Snapshots Archive is a two-step process. First, I retrieve the snapshot from EBS Snapshots Archive to its original snapshot ID, using RestoreSnapshotTier API call or the management console. It takes between 24-72 hours to retrieve the snapshot from the archive, depending on the snapshot size. Once retrieved, the snapshot appears as a regular snapshot on my account. At this stage, I hydrate the retrieved snapshot into an EBS volume using the default snapshot restore or Fast Snapshot Restore (FSR) for expedited restores, just like usual.

A CloudWatch event is generated when the snapshot is restored. You may listen to this event to avoid pulling the status with the API.

A CreateVolume API call on an archived snapshot will fail. You must restore a snapshot from archive before you use it to create a volume.

Using the AWS Management Console, I select the snapshot that I want to restore, I select the Actions menu, and then I select the Restore snapshot from archive menu option.

EBS Snapshot Archive - create snapshot - restore archive

I have the choice to restore the snapshot permanently, or just temporarily. At the end of the temporary duration, the standard tier snapshot is deleted, and only the archive is preserved.

EBS Snapshot Archive - create snapshot - restore archive - confirmation

After a while, depending on the snapshot size, the archive is restored to standard storage and may be used to recreate a volume, just like usual. I may monitor the progress of the retrieval and the lifetime for temporarily restored archives in the new Storage tier tab in the bottom half of the screen. Temporary restored snapshots may be kept for up to 180 days.

Pricing and Availability
EBS Snapshots Archive is available for you today in 17 AWS Regions. At the time of launch, it is not available in the two Regions in China, Asia Pacific (Seoul), Asia Pacific (Osaka), Canada (Central), and South America (São Paulo).

As per usual, you pay as-you-go, with no minimum or fixed fees. There are two metrics that influence EBS Snapshots Archive billing: data storage and data retrieval. We charge you $0.0125 per GB-month of stored data and $0.03 per GB retrieved. You are charged for a 90-day period at minimum. This means that if you delete a snapshot archive or permanently restore it less than 90 days after creation, then we charge for the full 90-day period. The EBS pricing page has the details.
Go ahead and start to configure your long term storage for EBS snaphots today.

— seb