Tag Archives: AWS Glue

Automate data discovery and centralized management with AWS Glue Data Catalog

Post Syndicated from Ramakrishna Natarajan original https://aws.amazon.com/blogs/big-data/automate-data-discovery-and-centralized-management-with-aws-glue-data-catalog/

Managing sensitive data across sprawling data environments is hard. In this post, we show you how to tackle data discovery, classification, and governance across your databases, data warehouses, and object storage to regain visibility and control over your data landscape. As you build new features, products, and services, your data naturally spreads across multiple systems to meet immediate application and business needs. Different teams spin up their own data stores, and before long, you’re dealing with a complex web of repositories—often with limited visibility into what exists where. This data sprawl becomes most challenging when you must understand and protect your sensitive data. Security teams often struggle to maintain accurate inventories of data categorization and classification. Stakeholders demand comprehensive insights into data classification and processing activities, usually on tight deadlines, and keeping up-to-date data inventories becomes increasingly daunting as your data grows. Without automation, you’re left with manual processes that stretch over weeks, leave room for human error, and create unnecessary business risk.

The need for automation

In a typical manual scenario, creating a new database triggers a chain of time-consuming events. The governance team reviews the new data source, documents its contents, and scans for sensitive data. The security team assesses its configuration and access controls. Days or weeks pass before you fully understand this new asset’s sensitivity.

With automation, creating a new database triggers immediate action. The system detects the new source, catalogs its structure, identifies sensitive data, and updates a central inventory within minutes, supporting proper governance from the moment you create it. Here’s how it works on AWS: When you create an Amazon Simple Storage Service (Amazon S3) bucket for customer orders, you add tags such as Business Function, Data Owner, and Purpose. After the bucket is in use, the system detects it, creates catalog entries, analyzes data patterns, identifies sensitive information, and updates governance records without additional input from you. This gives your organization real-time visibility. Security teams instantly see which repositories contain sensitive information. Governance teams generate up-to-date inventory reports on demand, and data teams immediately understand sensitivity levels, helping them use data responsibly.

Solution overview

The solution uses key AWS services across three layers that work together for comprehensive data visibility and categorization.

Detection Layer: Continuously monitors your AWS environment for new resource creation. When you provision an Amazon S3 bucket, Amazon Relational Database Service (Amazon RDS) database, or Amazon DynamoDB table, Amazon EventBridge rules capture this activity and initiates the governance workflow, so no data source goes unnoticed.
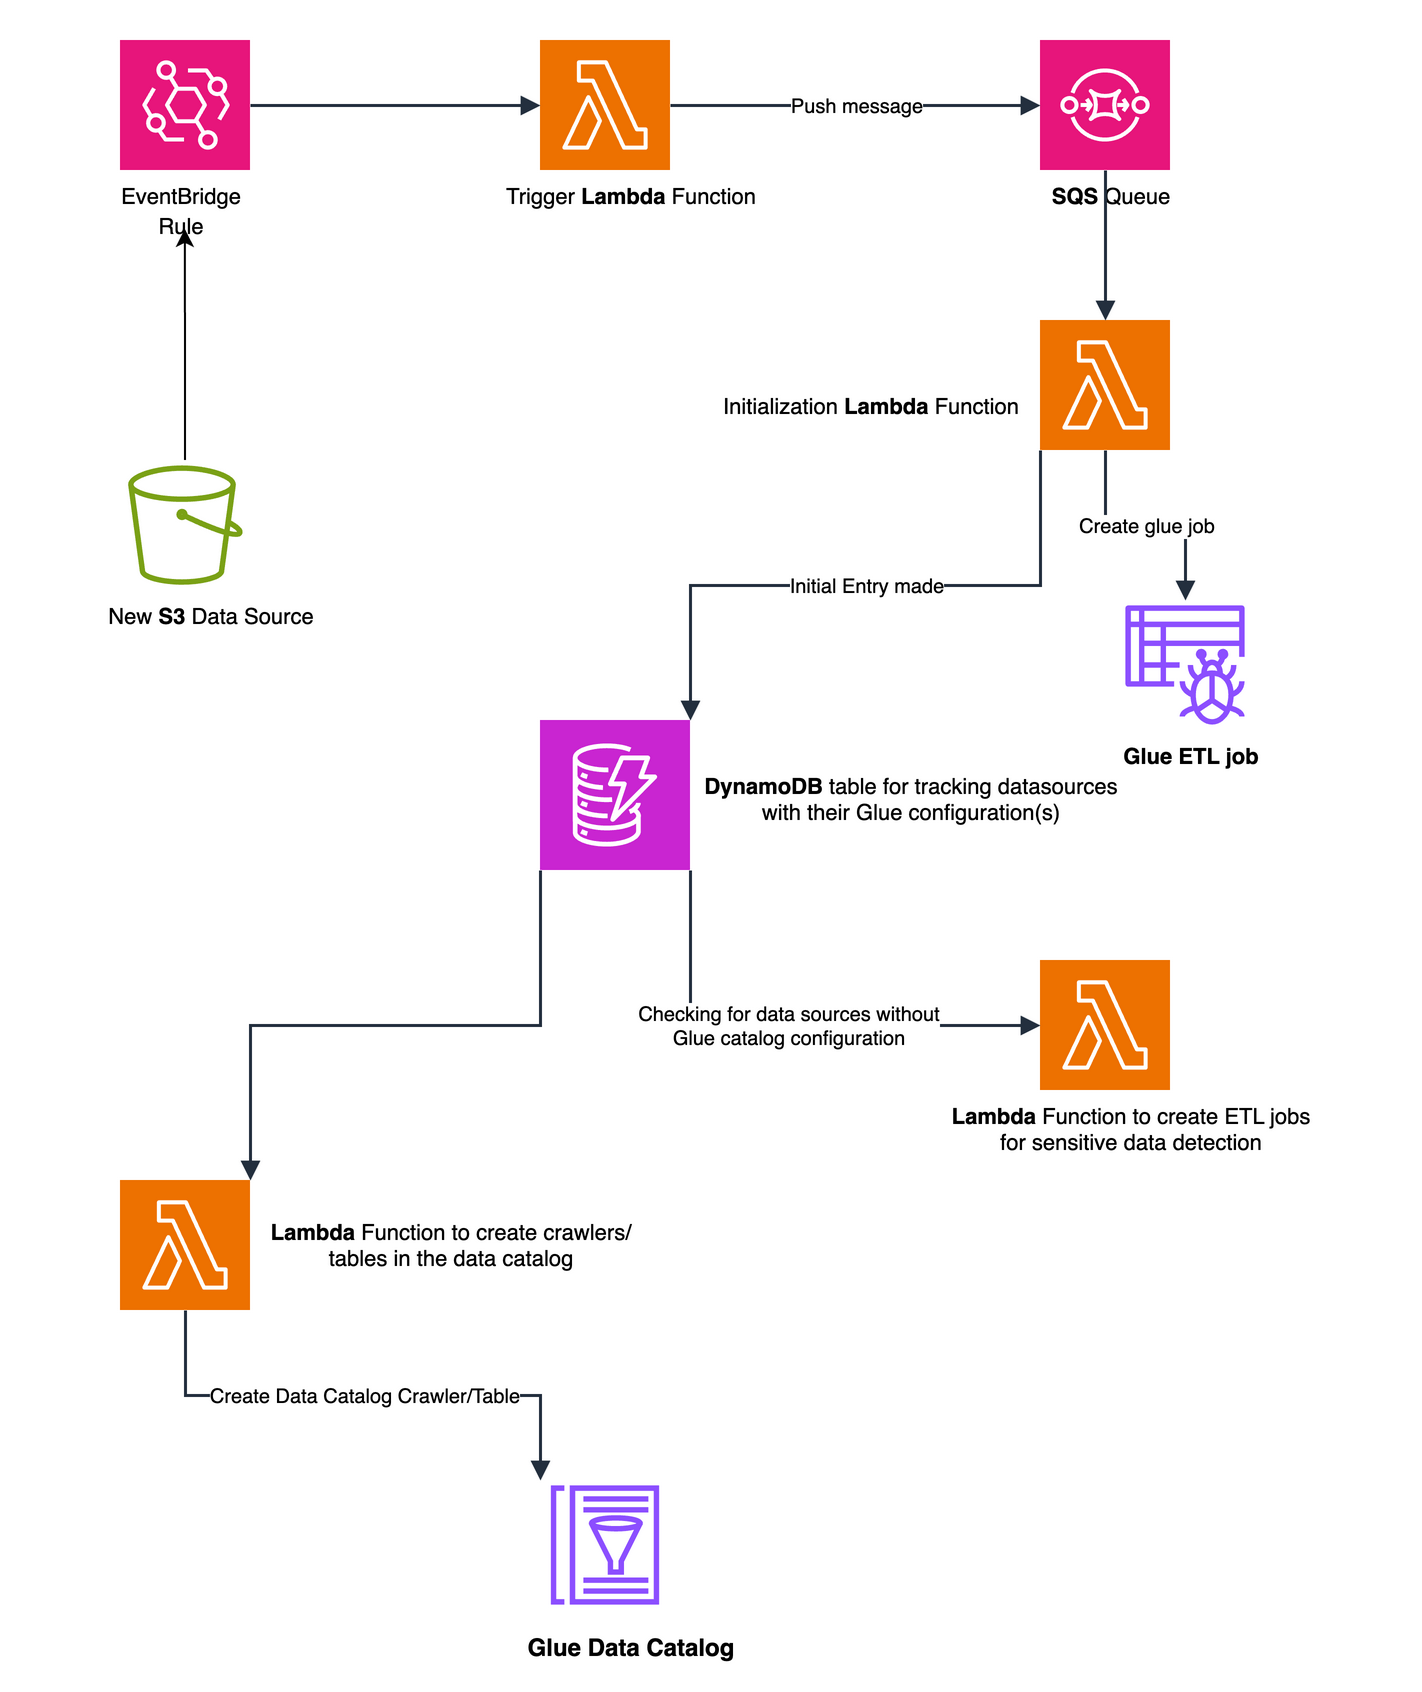
Architecture: EventBridge triggers Lambda and SQS to create Glue crawlers and ETL jobs for new S3 data sources
Figure 1 Automated data source discovery (S3 example) workflow using EventBridge Rules and Lambda functions

Processing Layer: After a new source is detected, AWS Glue crawlers analyze its schema while specialized jobs scan for sensitive data patterns. The system also extracts metadata from resource tags, enriching your understanding of each repository’s purpose and ownership.
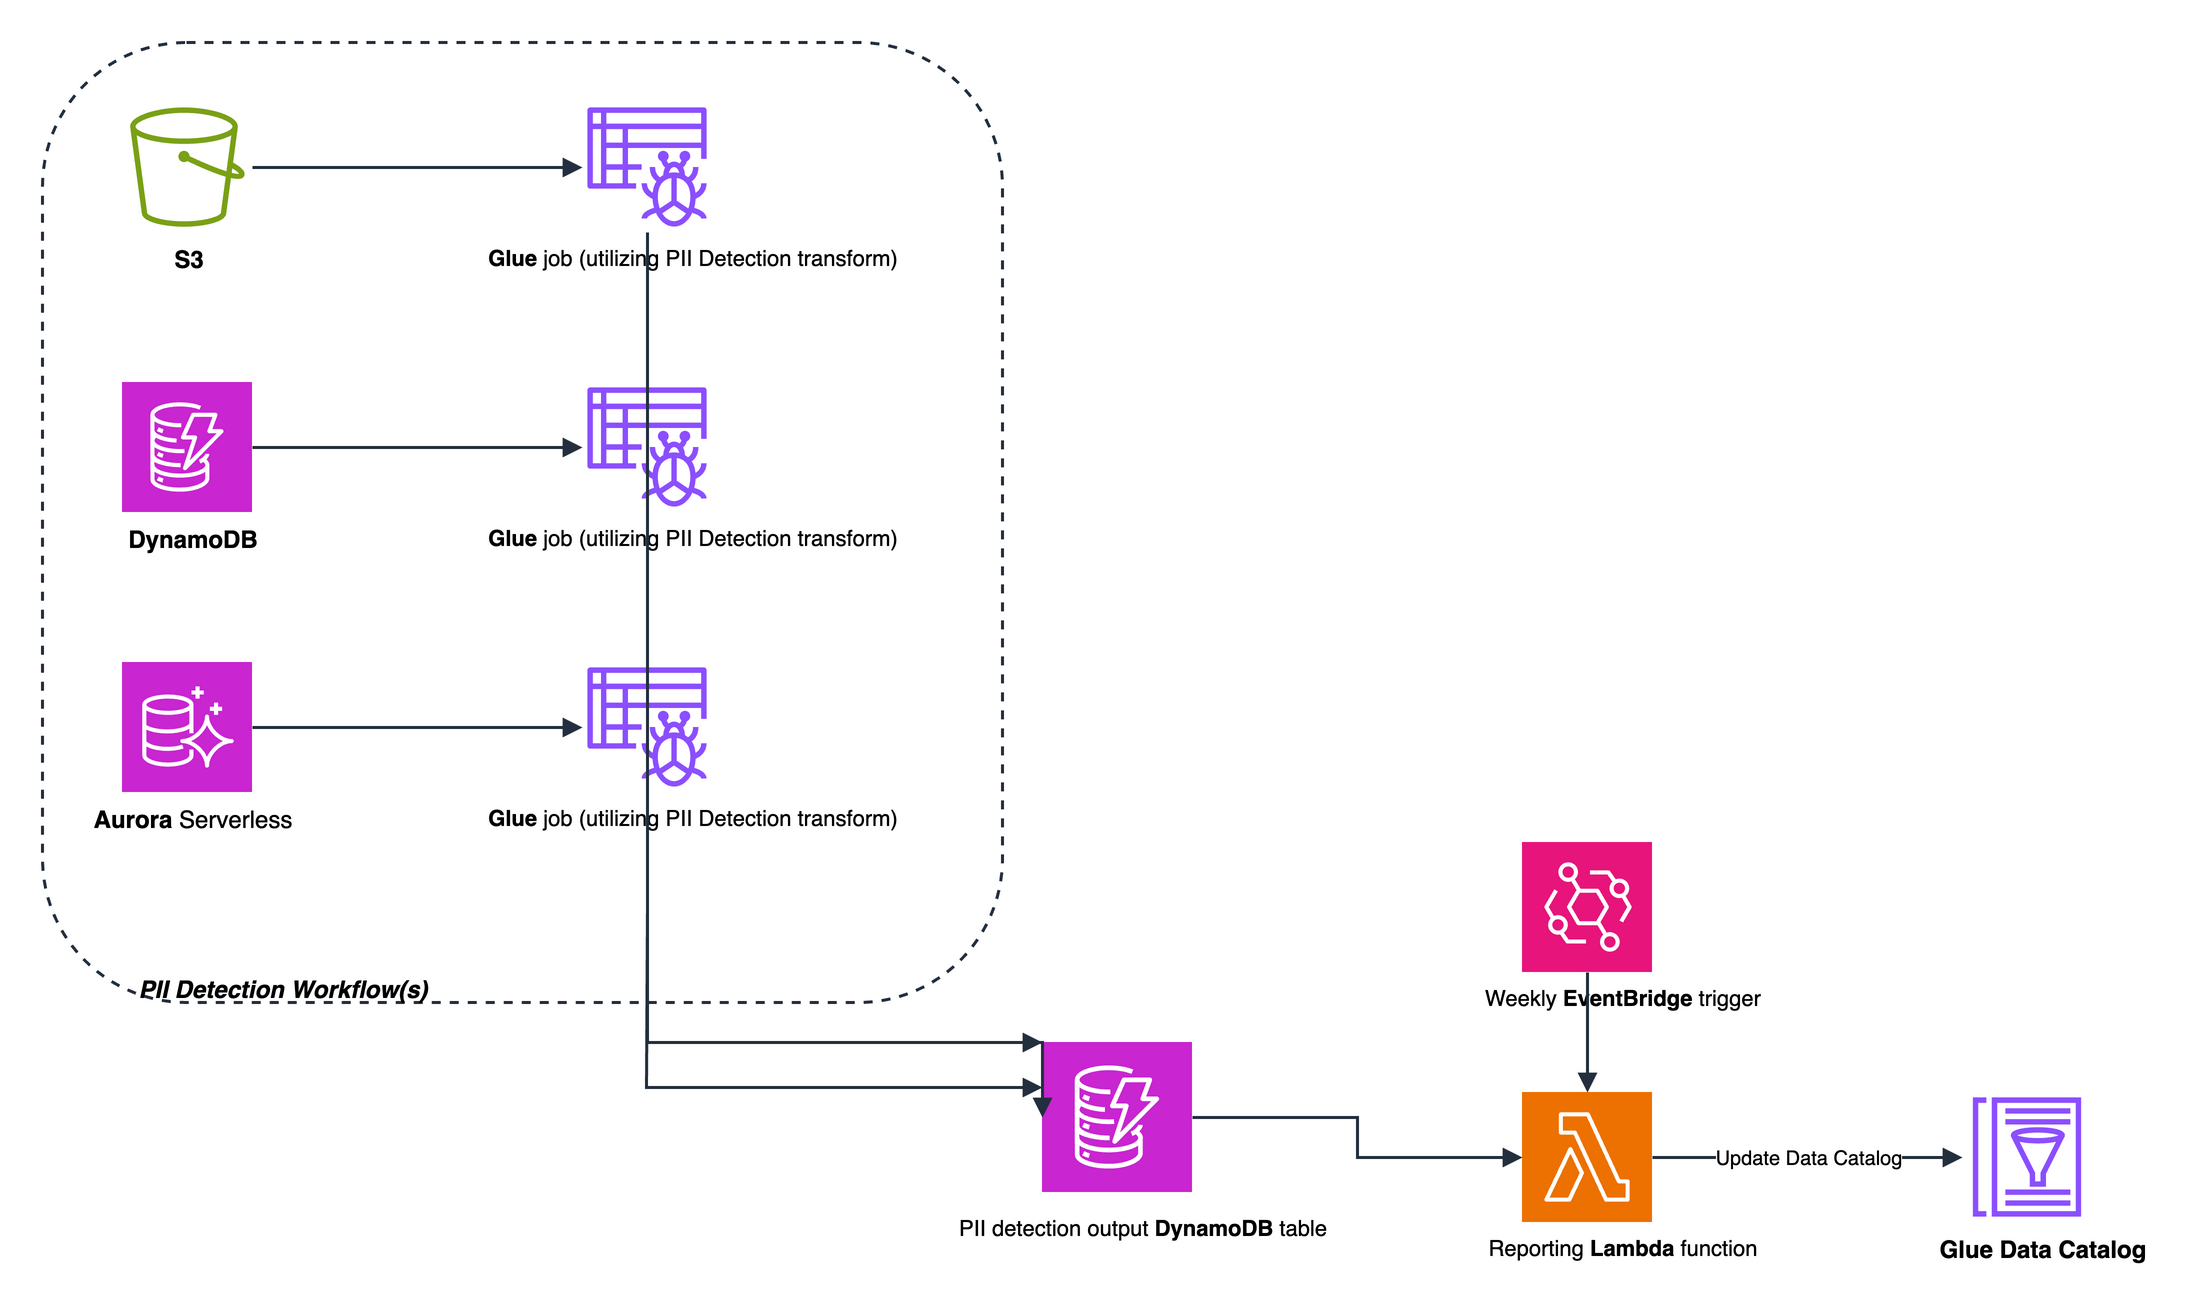
Architecture: Glue PII Detection jobs scan S3, DynamoDB, and Aurora; Lambda updates Glue Data Catalog
Figure 2 PII detection and processing workflow using AWS Glue jobs and DynamoDB staging

Management Layer: Maintains a central source of truth about your data assets. AWS Glue Data Catalog provides a unified view across your organization, tracking schema changes and sensitivity levels. This layer also manages the processing workflow state and generates insights for stakeholders.
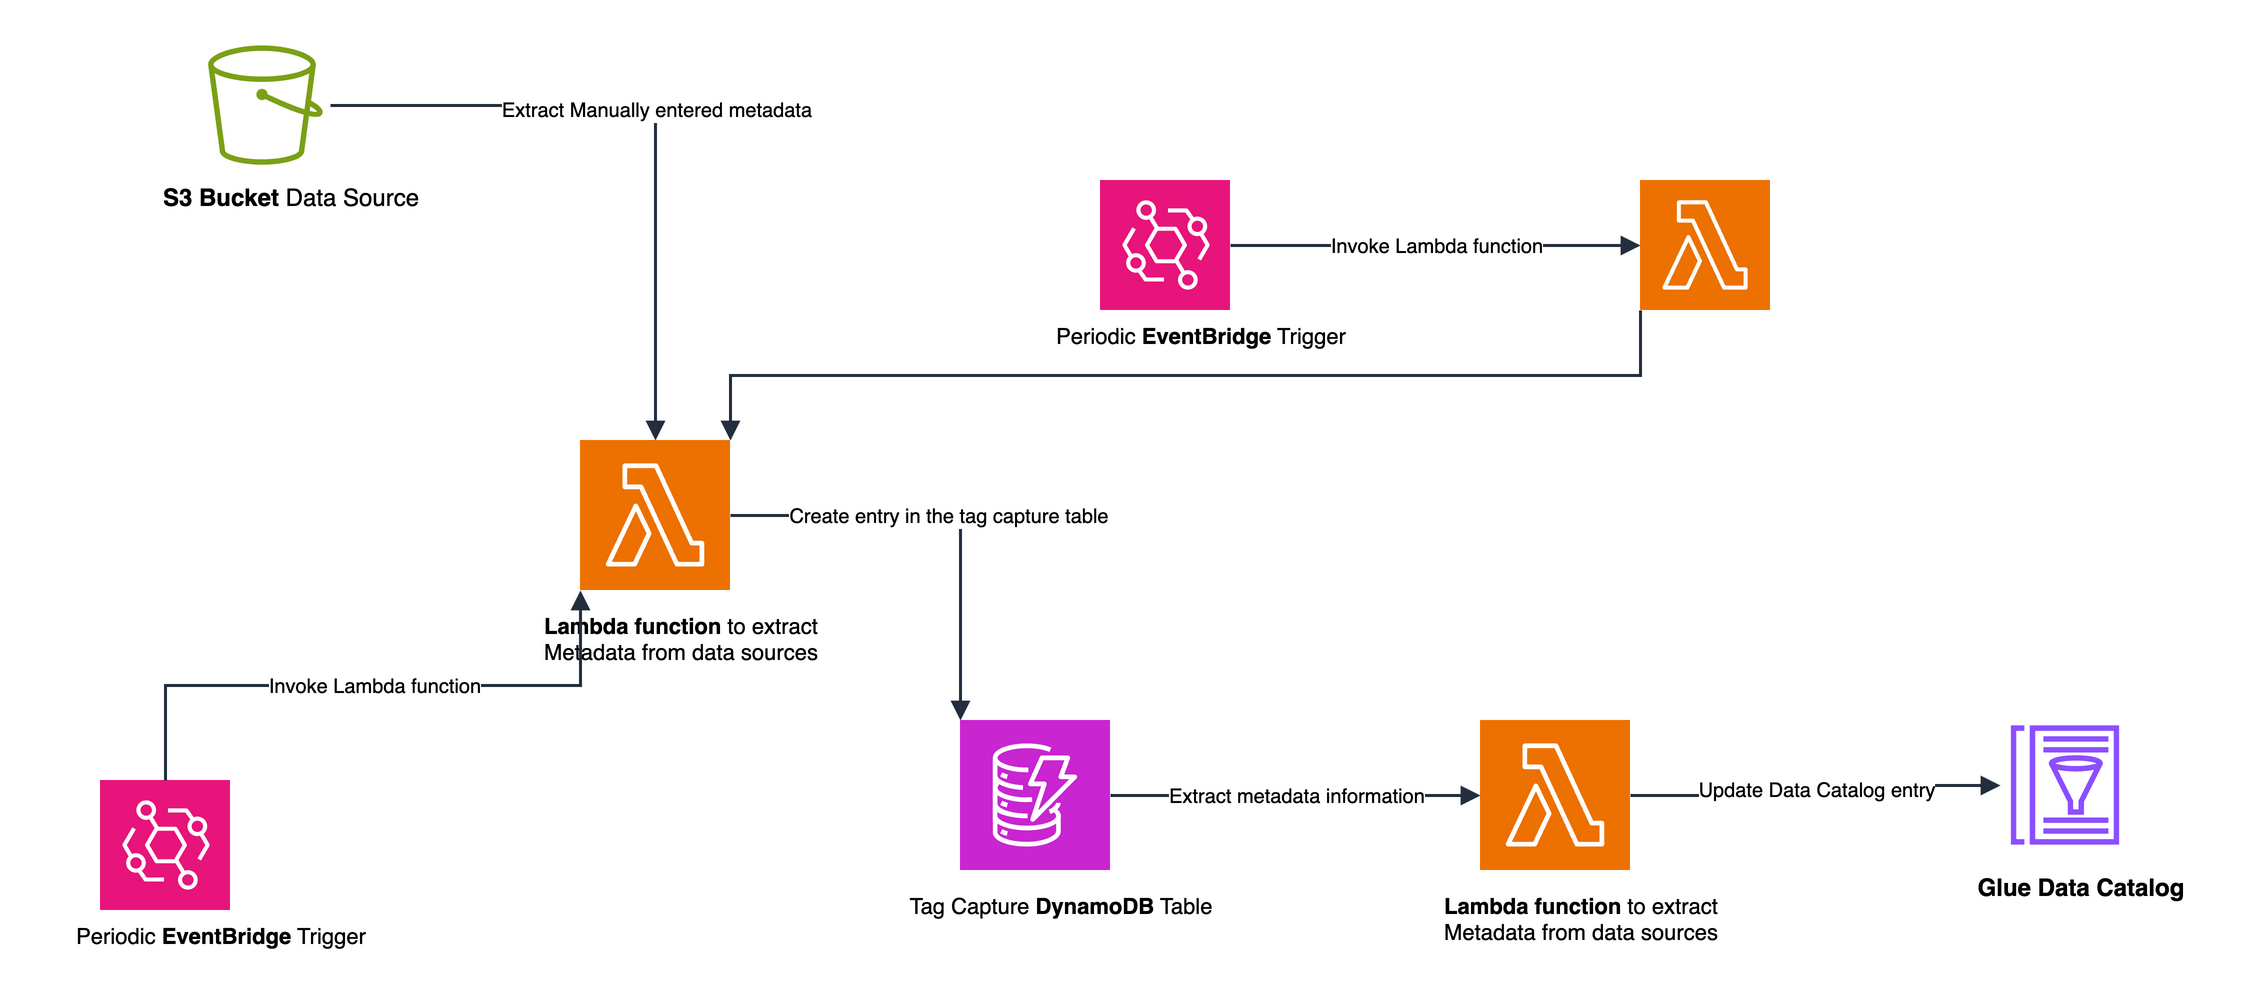
Architecture: Lambda extracts S3 bucket metadata via EventBridge, stores in DynamoDB, updates Glue Data Catalog
Figure 3 Tag-based metadata capture and Data Catalog update workflow

Setting up the solution

This solution uses AWS Cloud Development Kit (AWS CDK) for deployment, organized into four stacks that build upon each other.PrerequisitesBefore deployment, verify that you have:

  • Access to an AWS account with permissions to create resources in Amazon S3, AWS Lambda, Amazon DynamoDB, AWS Glue, and Amazon EventBridge
  • Node.js (version 18 or later) and npm installed
  • Access to a terminal to run AWS CDK CLI commands
  • Basic familiarity with AWS Console navigation

Step 1: Infrastructure deployment

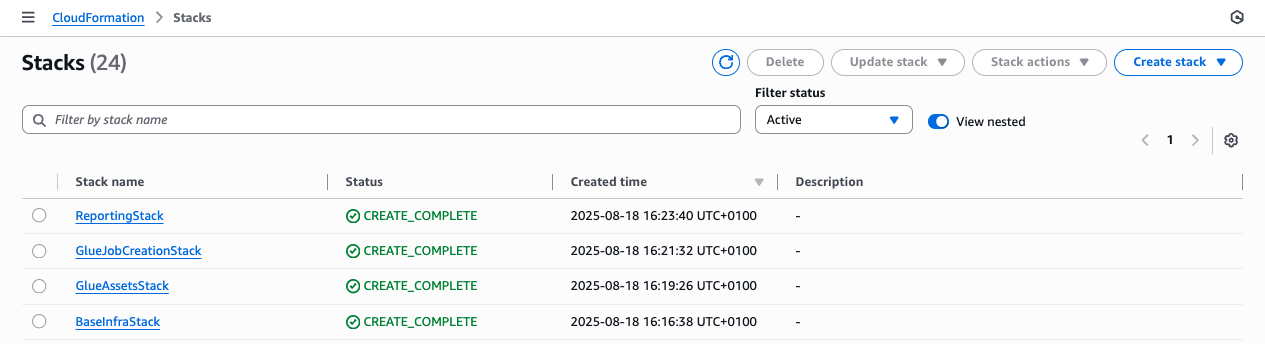
Deploy four stacks using AWS CDK. Each establishes components for data discovery, cataloging, and PII detection.

  1. BaseInfraStack: Deploys core infrastructure—Amazon Virtual Private Cloud (Amazon VPC), DynamoDB tables for state management, EventBridge rules for monitoring, and Lambda functions for orchestration.
  2. GlueAssetsStack: Sets up S3 buckets for AWS Glue ETL scripts and deploys PySpark code for PII detection.
  3. GlueJobCreationStack: Creates Data Catalog databases and deploys Lambda functions that automate the creation of AWS Glue crawlers and PII detection jobs for newly discovered data sources.
  4. ReportingStack: Deploys Lambda functions that process PII detection results and tag metadata, updating the Data Catalog accordingly.

To deploy these stacks, you will use the AWS CDK CLI, running the following commands:
# Clone and prepare repository
git clone https://github.com/aws-samples/automated-datastore-discovery-with-aws-glue.git
cd automated-datastore-discovery-with-aws-glue
npm install
npx cdk bootstrap

# Deploy infrastructure stacks sequentially
npx cdk deploy BaseInfraStack
npx cdk deploy GlueAssetsStack
npx cdk deploy GlueJobCreationStack
npx cdk deploy ReportingStack
CloudFormation Stacks console showing four stacks with CREATE_COMPLETE status including BaseInfraStack

Figure 4 CloudFormation console showing successful stack deployment

Step 2: Verify initial setup

In the AWS Management Console, open DynamoDB and find the glueJobTracker table. This table is a critical component of the framework:

  • Purpose: Central state management – tracks processing states and configurations for discovered data sources.
  • Current state: The table should be empty because no discovery processes have been triggered yet.
  • Structure: Tracks states such as Data Catalog entry creation and PII detection job setup for each data source.

By verifying this table, you confirm that the infrastructure is ready to begin tracking new data sources.
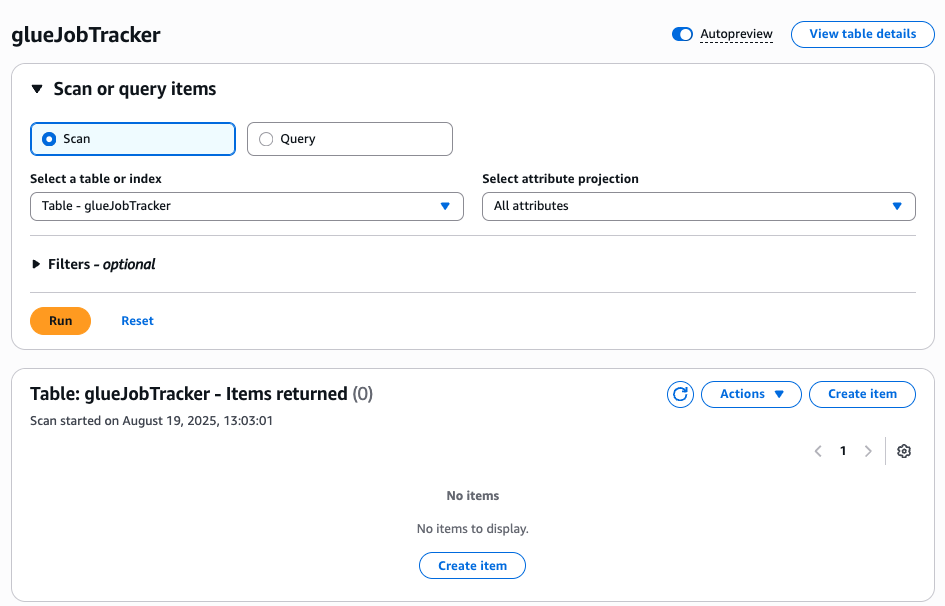
DynamoDB glueJobTracker table scan returning zero items, showing empty table before pipeline execution

Figure 5 Empty DynamoDB glueJobTracker table before execution

Solution in action

This solution runs automatically in production through EventBridge triggers and scheduled AWS Glue crawlers. The following walkthrough executes each step manually so you can observe the workflow.You follow the journey of a newly created S3 bucket containing sensitive data, seeing how the solution discovers, catalog, and processes it through each stage.

Step 3: Create a new S3 bucket

  1. Open the Amazon S3 console.
  2. Choose Create bucket.
  3. Enter a unique name for your bucket (for example, demo-customer-data-20250819).
  4. In the Tags section, add the following tags:
    1. Key: gdpr-scan, Value: true
    2. Key: Business Function, Value: Sales – US
    3. Key: Data Classification, Value: Confidential
  5. Keep other settings as default and choose Create bucket.
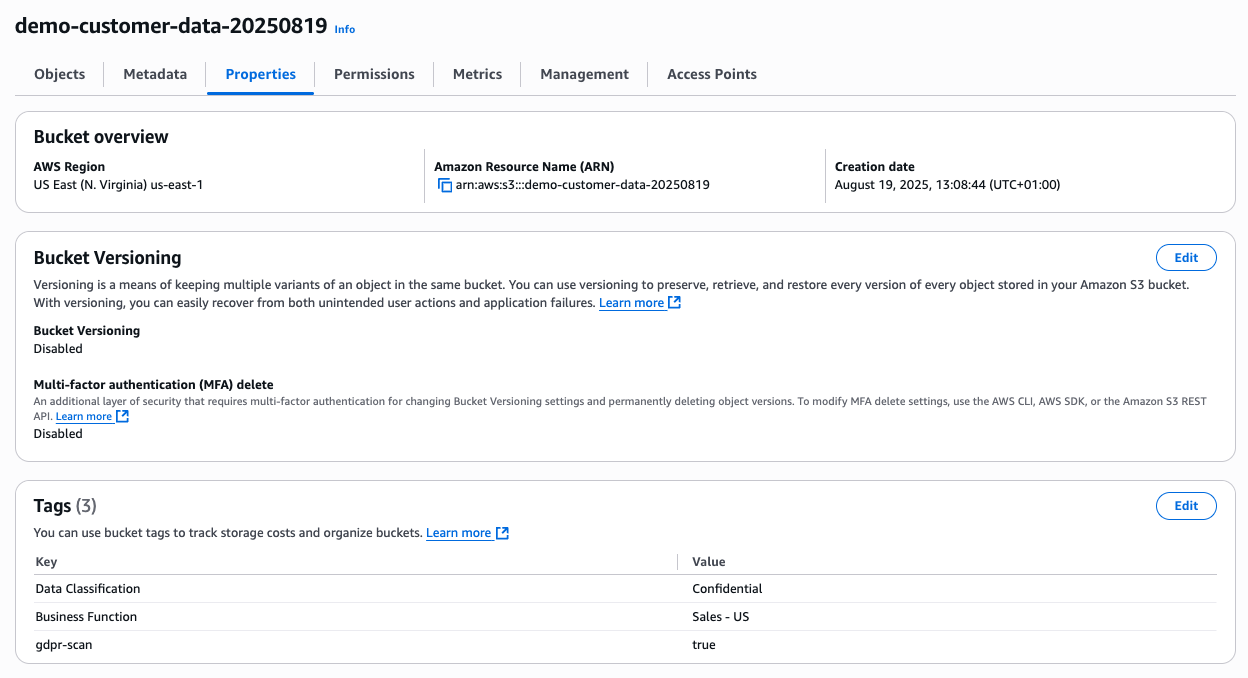
S3 bucket properties with versioning disabled and data classification tags

Figure 6 S3 console showing new bucket creation with tags

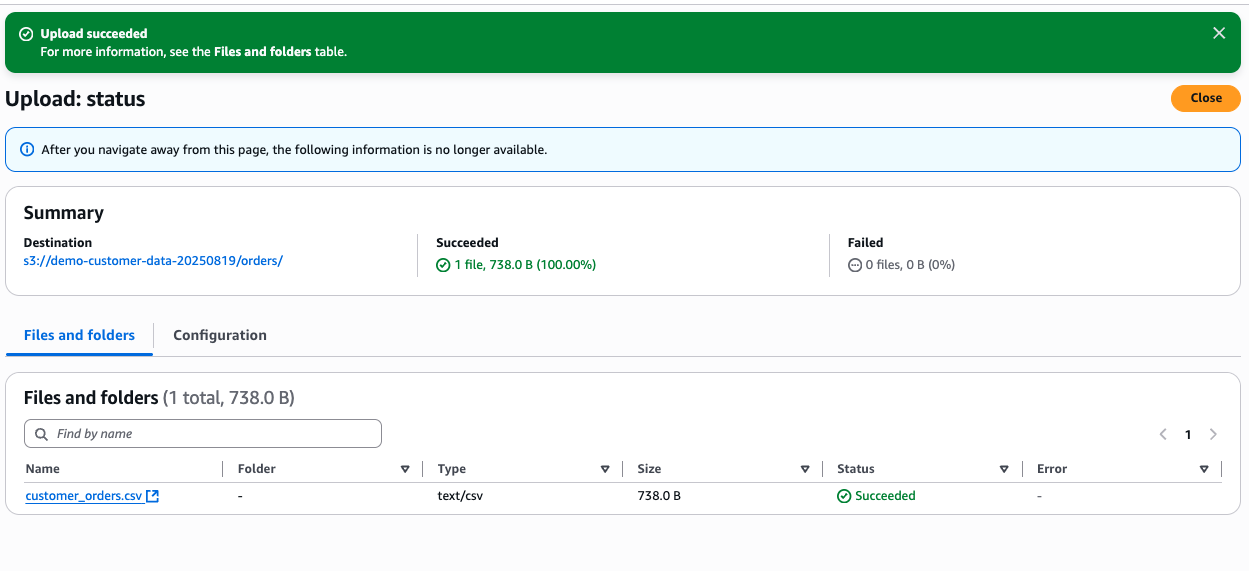
Step 4: Upload sample data

  1. In the S3 console, open your newly created bucket.
  2. Choose Upload.
  3. Create a new file named customer_orders.csv with the below content.
  4. Upload this file to a folder named orders/ in your bucket.
order_id,customer_id,email,ssn
ORD001,CUST1001,[email protected],***-**-****
ORD002,CUST1002,[email protected],***-**-****

S3 upload succeeded showing customer_orders.csv uploaded

Figure 7: S3 console showing uploaded CSV file in the orders folder

Step 5: Verify automated detection

  1. Open the DynamoDB console.
  2. Navigate to the glueJobTracker table.
  3. Choose the Items tab.
  4. You should see a new item with an s3_location matching your bucket name.
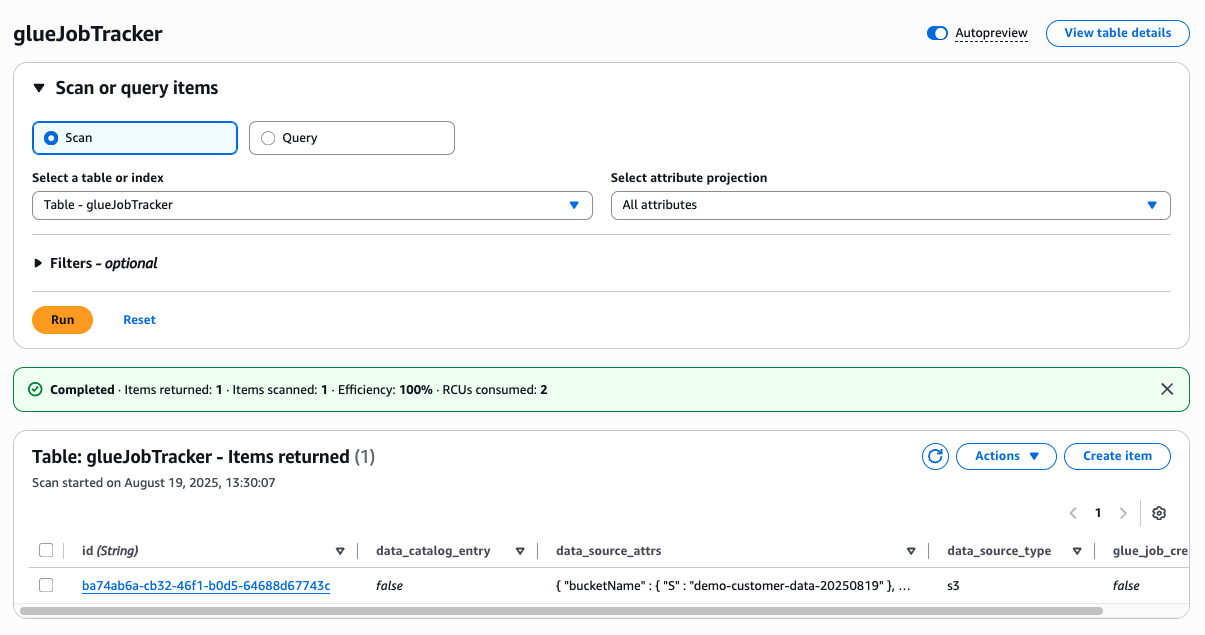
40918.pngDynamoDB glueJobTracker table scan returning 1 item with S3 data source entry

Figure 8 DynamoDB console showing detected bucket entry in glueJobTracker table

Step 6: Initiate catalog creation

  1. Open the AWS Lambda console.
  2. Find the function with a name containing s3GlueCatalogCreator.
  3. Choose the function name to open its details.
  4. Choose the Test tab.
  5. Create a new test event with an empty JSON object {}.
  6. Choose Test to invoke the function.
  7. Check the execution result for a successful response.
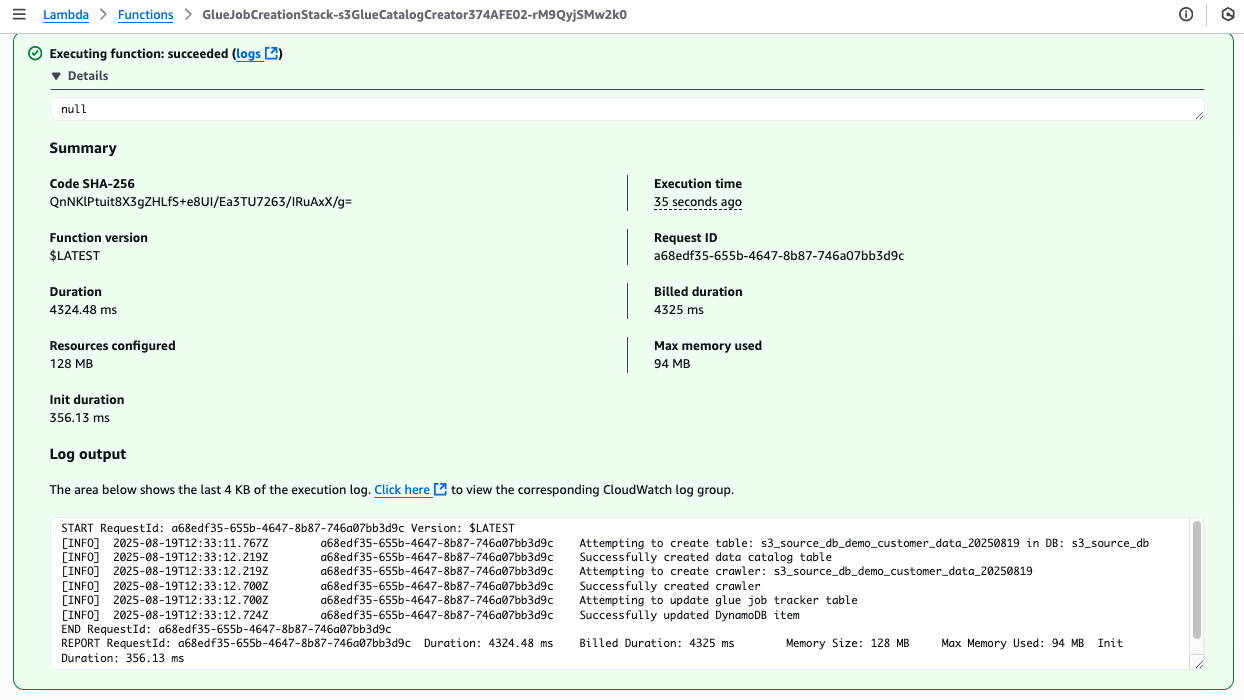
Lambda function execution succeeded with logs showing Glue table, crawler, and DynamoDB item creation

Figure 9 Lambda console showing successful function execution

Step 7: Run the AWS Glue crawler

  1. Navigate to the AWS Glue console.
  2. In the left sidebar, choose Crawlers.
  3. Find the crawler with a name related to your S3 bucket.
  4. Select the crawler and choose Run crawler.
  5. Wait for the crawler to complete (typically 3–5 minutes).
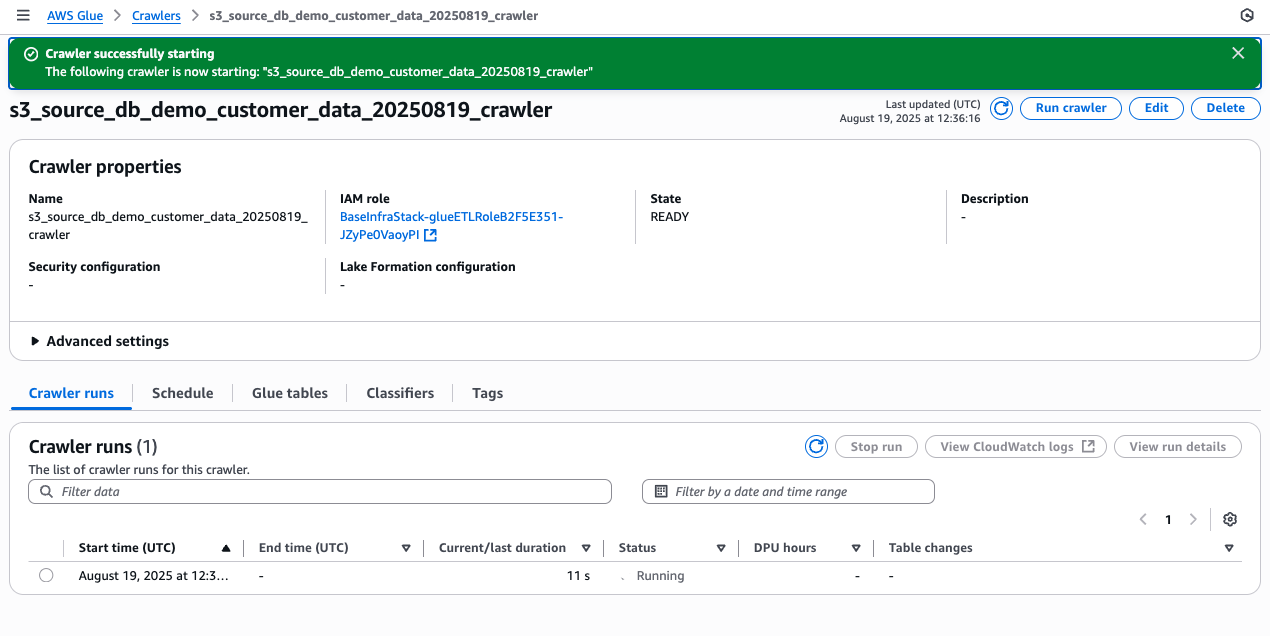
AWS Glue crawler running

Figure 10 Glue console showing crawler in “Running” state

Step 8: Verify schema discovery

  1. In the AWS Glue console, go to Databases in the left sidebar.
  2. Choose the s3_source_db database.
  3. You should see a new table corresponding to your uploaded data.
  4. Choose the table name to view its schema.
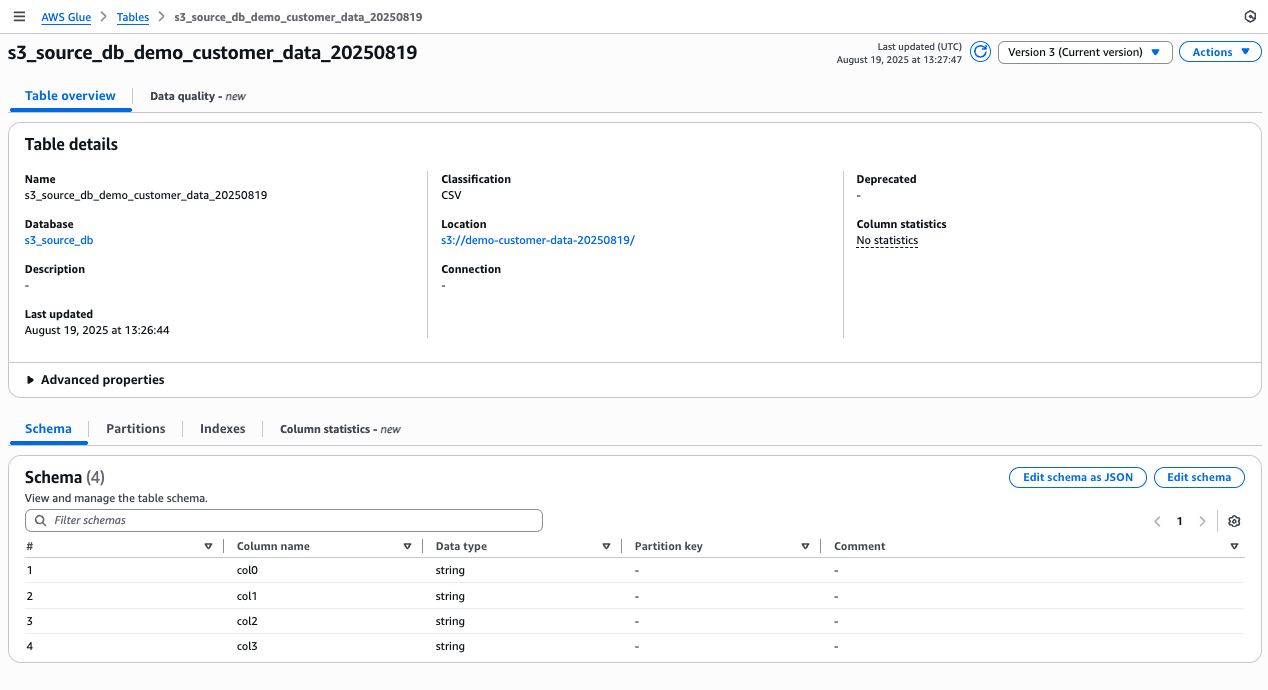
Glue Data Catalog table Version 3 showing 4-column CSV schema with no sensitive data annotations yet

Figure 11 Glue console showing detected table schema

Step 9: Execute PII detection

  1. Return to the Lambda console.
  2. Find and open the function with a name containing s3GlueCreator.
  3. Use the Test tab to invoke this function with an empty JSON object {}.
  4. After successful execution, go to the AWS Glue console.
  5. Navigate to Jobs in the left sidebar.
  6. Find the newly created PII detection job (it should contain your bucket name).
  7. Select the job and choose Run job.
  8. Monitor the job execution in the Glue console.
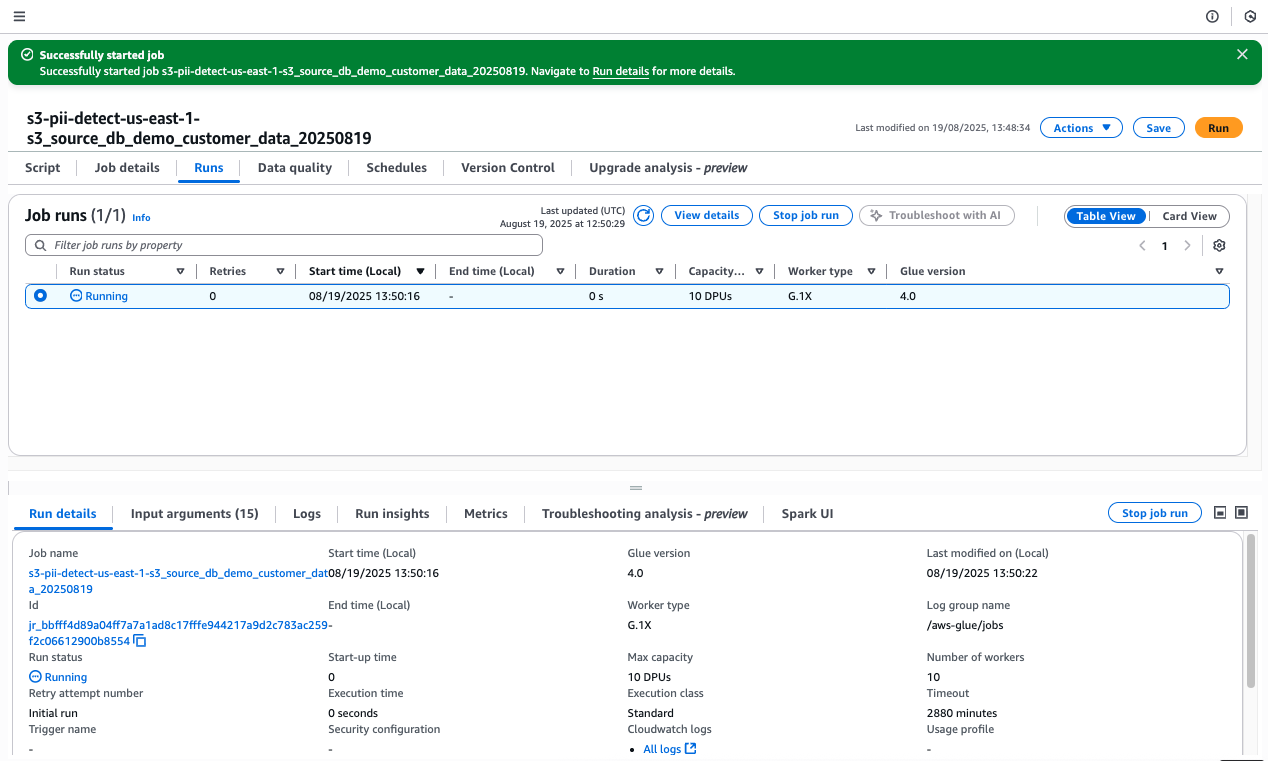
AWS Glue PII detection job running with 10 DPUs, G.1X worker type, Glue version 4.0, showing run details

Figure 12 Glue console showing PII detection job in “Running” state

Step 10: Review PII detection results

  1. Open the DynamoDB console.
  2. Navigate to the piiDetectionOutputTable.
  3. In the Items tab, you should see new entries related to your data.
  4. These entries will show detected PII types and confidence scores.
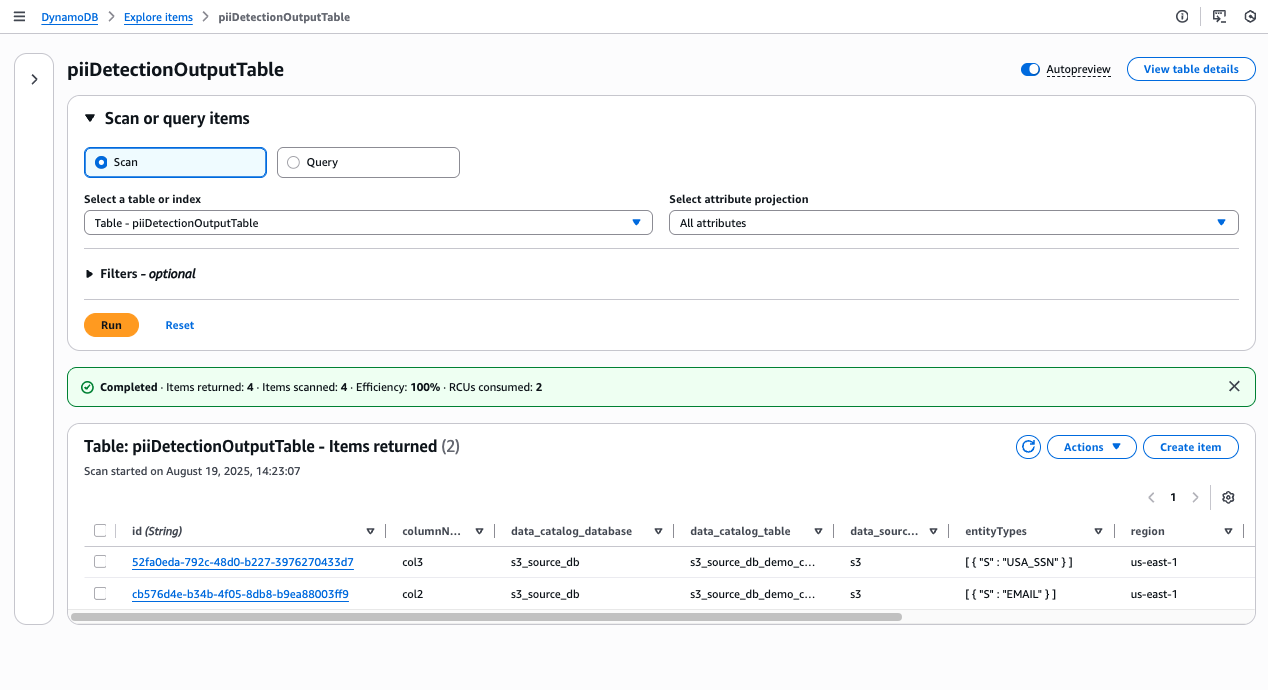
DynamoDB piiDetectionOutputTable scan showing 2 PII detection results identifying USA_SSN and EMAIL types

Figure 13 DynamoDB console showing PII detection results in piiDetectionOutputTable

Step 11: Verify Data Catalog updates

  1. Open the AWS Lambda console.
  2. Find the function with a name containing ReportingStack-PIIReportS3.
  3. Choose the function name to open its details.
  4. Choose the Test tab.
  5. Create a new test event with an empty JSON object {}.
  6. Choose Test to invoke the function.
  7. Check the execution result for a successful response.
  8. Return to the AWS Glue console.
  9. Go to Databases > s3_source_db > Your table.
  10. Review the schema. PII columns should now have comments indicating their classification.
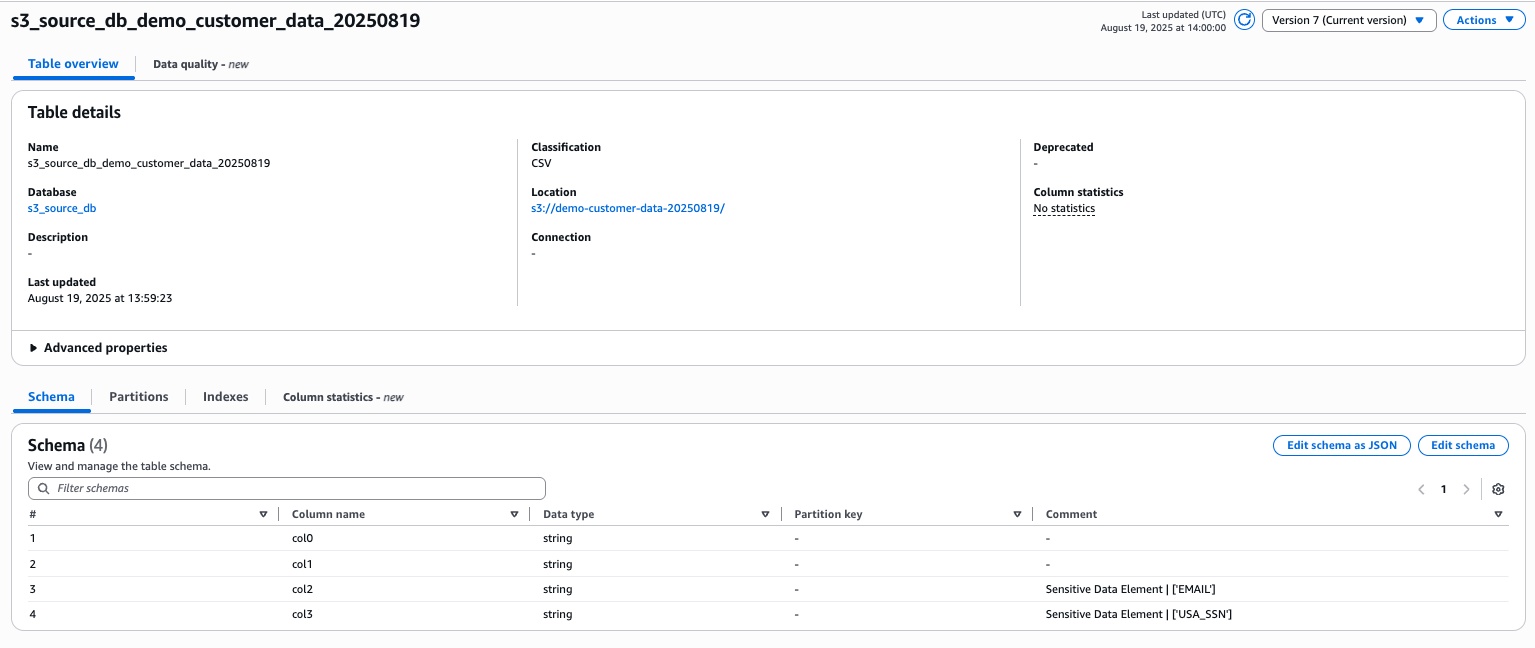
Glue Data Catalog table Version 7 with schema showing sensitive data element comments for EMAIL and USA_SSN

Figure 14 Glue console showing updated table schema with PII classifications

Note: While we focus on S3 data sources in this walkthrough, the framework extends to other data stores, offering a unified approach for PII detection and compliance management, so organizations can automatically discover, catalog, and monitor sensitive data elements across your entire data ecosystem. For more information, see aws-samples/automated-datastore-discovery-with-aws-glue.

Best practices and operational excellence

As you implement this solution, consider these key practices for effective results:

  • Design your tagging strategy to capture essential business context about each data source. Implement automated tag enforcement through AWS Organizations for consistency across teams.
  • Monitor automated workflows regularly and configure retention policies for processed data to manage costs.
  • For enhanced security, configure VPC endpoints for services such as Amazon S3, DynamoDB, and other data sources. This keeps traffic within the AWS network, which is especially important when processing sensitive data. Verify that server-side encryption (SSE) is enabled on your data stores. This solution uses AWS Key Management Service (AWS KMS) keys for DynamoDB tables and SSE-S3 for S3 buckets by default, aligning with data-at-rest encryption best practices.
  • For teams with multiple AWS accounts, implement cross-account discovery and cataloging to maintain a comprehensive view of your data landscape.
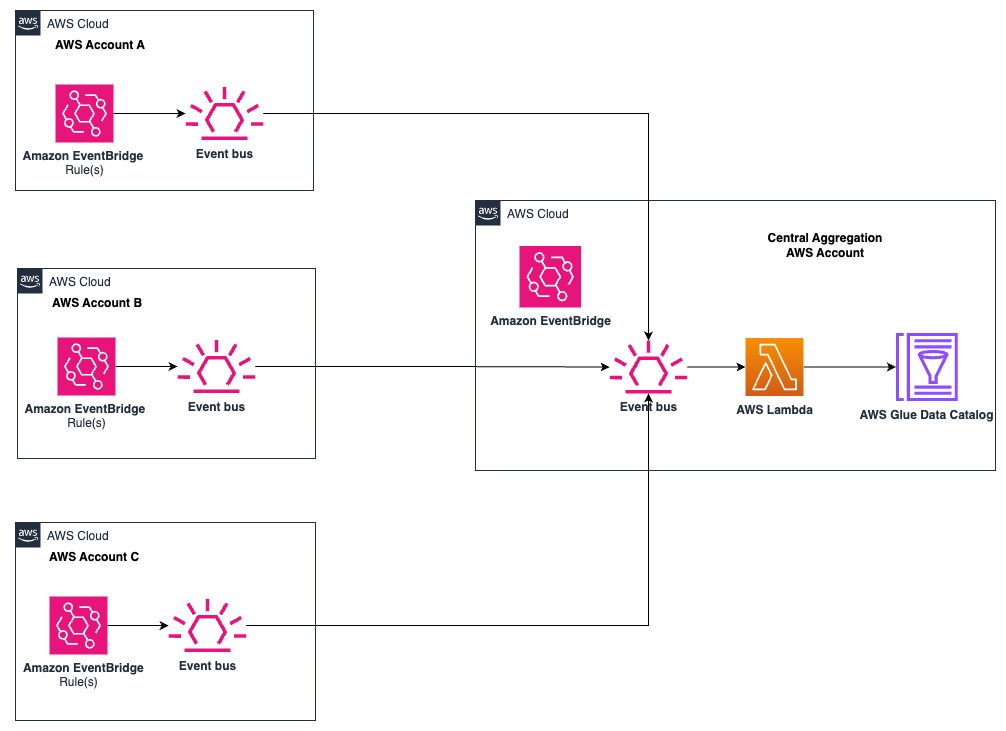
Multi-account EventBridge buses aggregate events to central account with Lambda and Glue Data Catalog

Figure 15 Centralized Storage of Glue PII Detection Results in AWS Data Catalog

Clean up

To avoid ongoing charges and remove the resources created by this solution, follow these steps:

  1. Empty and delete the S3 buckets created for sample data and AWS Glue assets.
  2. Delete the AWS CloudFormation stacks in reverse order of creation:
    1. ReportingStack
    2. GlueJobCreationStack
    3. GlueAssetsStack
    4. BaseInfraStack
  3. Manually delete any remaining resources:
    1. DynamoDB tables (glueJobTracker, piiDetectionOutput, tagCaptureTable)
    2. AWS Glue databases and crawlers
    3. Lambda functions
    4. EventBridge rules
  4. Review your AWS account to ensure that all related resources have been removed.

Remember, deleting these resources will remove all data and configurations associated with this solution. Make sure that you have saved any important information before proceeding with the clean-up.

Conclusion

In this post, you learned how to build an automated data governance framework using AWS Glue Data Catalog. You set up detection, processing, and management layers that automatically discover, catalog, and classify your data sources.This approach improves how you manage sensitive data assets. Teams spend less time on manual discovery and categorization, freeing them to derive value from data. The system gives you current insights into your data landscape and automatically identifies sensitive data, creating a trusted source of truth that helps teams work efficiently while maintaining controls.You can extend this framework with custom sensitivity patterns for your industry. Its modular design supports continuous improvement and integrates with existing workflows. This turns data governance from a manual burden into an efficient process that scales with your organization.
About the authors

Ramakrishna Natarajan

Ramakrishna Natarajan

Ramakrishna is a Senior Partner Solutions Architect at Amazon Web Services. He is based out of London and helps AWS Partners find optimal solutions on AWS for their customers. He specialises in Telecommunications OSS/BSS and has a keen interest in evolving domains such as Data Analytics, AI/ML, Security and Modernisation. He enjoys playing squash, going on long hikes and learning new languages.

Securing client confidentiality at scale: Automated data discovery and governed analytics for legal workloads

Post Syndicated from Rohan Kamat original https://aws.amazon.com/blogs/big-data/securing-client-confidentiality-at-scale-automated-data-discovery-and-governed-analytics-for-legal-workloads/

Automating data security and analytics for legal documents presents a unique challenge when your legal team stores documents with strong access controls, organized by client and matter, encrypted at rest, and governed by well-defined policies. But what happens when you want to run analytics across those repositories? The typical path is extracting content into separate data pipelines or third-party tools, which fragments your governance model and introduces new risks. Law firms and corporate legal departments operate under distinct obligations that make data governance non-negotiable. Attorney-client privilege, work product doctrine, and professional conduct rules impose strict duties around how client information is handled, accessed, and disclosed. Governance failure in this context isn’t just a compliance gap, it can result in privilege waiver, disqualification from representation, or disciplinary action.

Legal professionals use ethical walls, also called information barriers, as structural safeguards that prevent the flow of confidential information between teams within a firm that represent adverse or potentially conflicting interests. Professional conduct rules mandate these barriers, and failure to maintain them can result in firm disqualification, malpractice liability, or regulatory sanctions.

Privilege boundaries are equally critical. Attorney-client privilege and work product protection apply only when you properly control access to the underlying material. If you expose privileged documents or metadata about their contents to unauthorized individuals, you risk losing your privilege protection. When organizations fail to maintain reasonable controls over privileged material, courts might find that they have waived their privilege. You should therefore actively manage your access governance, not only as a security concern but as a legal preservation requirement.When you extract content into separate analytics systems or grant broader access than your matter structures support, you create pressure on both protections. You gain visibility but lose confidence in your controls.

In this post, we show you a reference architecture that automates sensitive data discovery across legal document repositories on Amazon Web Services (AWS), demonstrate how to capture structured findings as a compliance dataset, and guide you through building a governed analytics workspace that maintains your security boundaries. You walk away with a practical model for building security and analytics into the same lifecycle, without moving documents outside their system of record.

Analytics shouldn’t weaken governance

Most legal organizations have invested heavily in securing their document repositories. You store documents in structured storage, organized by client and matter. You access controls map to matter boundaries (the organizational and access structures that separate one client engagement from another). You establish retention and hold policies.The difficulty starts when teams want to analyze what’s inside those repositories. Running analytics typically means copying content into a separate system, standing up a new data pipeline, or granting broader access than existing matter structures support. Each of these steps introduces governance gaps. Manual reporting fills some of the void, but it doesn’t scale and can’t provide continuous visibility. What’s missing is a model where security controls and analytics reinforce each other, where the act of discovering sensitive data also produces the dataset that you use for reporting, and where governance applies once and carries through every downstream operation.

Automation addresses this by combining continuous sensitive data discovery with governed analytics, built on discovery metadata rather than document copies. This automated approach delivers four key advantages:

  • No document movement. Your files stay in their system of record. Analytics runs against structured discovery metadata, not document content, so governance boundaries remain intact.
  • Continuous discovery instead of manual scanning. Automated classification identifies regulated and sensitive information on an ongoing basis, replacing periodic manual reviews with on demand visibility.
  • Unified governance. You define matter-aligned access policies once, and they carry through from document storage to findings analytics and compliance reporting.
  • Built-in audit readiness. A durable record of discovery findings and remediation actions accumulates automatically over time, giving you structured evidence for client reviews and regulatory inquiries.

Reference Architecture

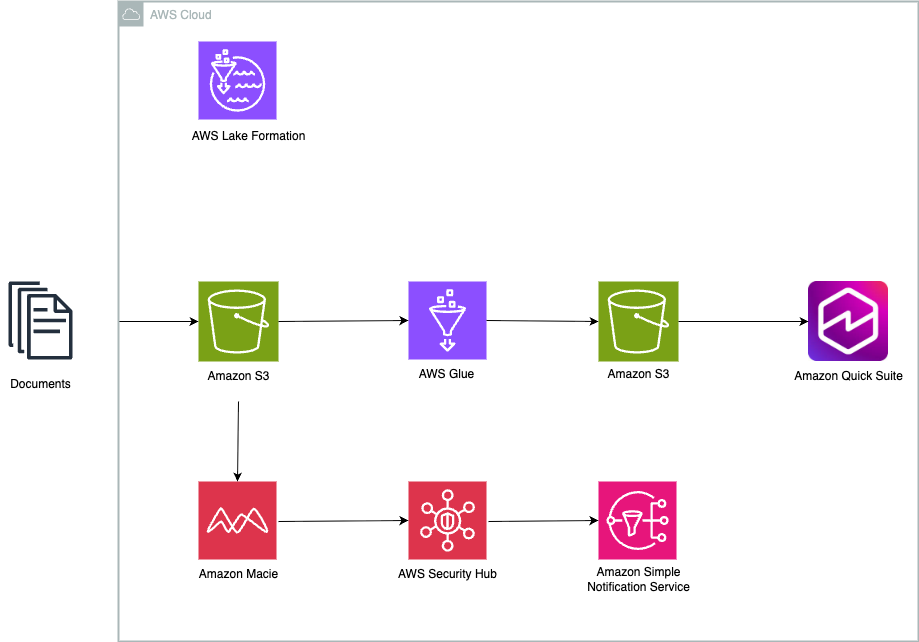
The following architecture shows how continuous discovery, governance, and compliance operations can work together without copying legal documents into analytics systems.

This reference architecture illustrates how law firms and corporate legal departments can automate sensitive data discovery and compliance analytics on AWS without moving documents outside their system of record

Architecture walkthrough

Store and protect documents in Amazon Simple Storage Service (Amazon S3)

Store your legal documents in Amazon S3, which serves as the system of record for document content. Align your buckets and prefixes to client and matter structures so that access controls map directly to matter boundaries. Where your retention or legal hold requirements demand it, apply S3 Object Lock to enforce immutability. You can encrypt your data using AWS Key Management Service (AWS KMS), which gives you centralized control over encryption keys and policies.

Discover and classify sensitive data with Amazon Macie

You will configure Amazon Macie to continuously analyze your document repositories. Macie identifies regulated information such as personally identifiable information (PII), financial data, and other sensitive content and produces structured findings that describe what Macie identified and where it exists. This provides ongoing visibility into data exposure without requiring document movement or manual scanning.

Catalog and govern findings with AWS Glue and AWS Lake Formation

You will use AWS Glue to catalog the findings dataset and maintain its schema so it stays query-ready. Apply AWS Lake Formation tag-based policies to govern access, aligning tags to client, matter, and confidentiality tier. This approach enforces ethical walls and least-privilege access consistently across analytics and reporting activities.

AI-powered chat agent using Amazon Quick Suite

You can create custom chat agents to tailor conversational interfaces for specific legal business needs. These agents can be configured with legal-specific knowledge bases, connected to relevant document repositories, and customized with instructions appropriate for legal workflows. You can use this chat agent to interact with your legal documents through natural language conversation for capabilities like:

  • E-Discovery:Search and analyze large volumes of legal documents to quickly find relevant information across your document repository.
  • Contract Analysis:Review contracts and automatically extract key terms, clauses, and obligations to streamline your contract review process.

The chat agent can help you navigate complex document sets through conversational queries, making legal research and document review more efficient and accessible.

Analyze and report with Amazon Quick Sight

You will use Amazon Quick as your compliance operations workspace. Quick provides a unified environment where your teams can query findings, generate dashboards, track remediation actions, and produce audit-ready reports. The agentic AI capabilities of Amazon Quick can autonomously build analyses, surface anomalies across matters, generate executive summaries for client reviews, and proactively recommend remediation priorities based on finding severity and trends. Combined with built-in data stories for automated narrative generation and pixel-perfect paginated reports for regulatory submissions, Quick reduces the time from discovery to action while keeping your teams within a governed interface aligned to matter-based permissions. Rather than switching between separate visualization, workflow, and reporting tools, your legal and compliance teams can review findings, manage response activities, and collaborate all within a single workspace that respects ethical walls and privilege boundaries.

Escalate high-severity findings

For high-severity findings that demand immediate attention, route alerts through AWS Security Hub or Amazon Simple Notification Service (Amazon SNS) to trigger escalation workflows. This connects visibility directly to action when your teams identify sensitive data risks.

Why this approach works for legal

Documents stay where they belong. Your files remain in Amazon S3, aligned to client and matter boundaries. No content moves into separate analytics pipelines.Ethical walls remain intact. Because analytics is built on discovery findings and not document copies, you can govern access to findings using the same matter-aligned controls that apply to documents. Compliance and security teams gain visibility without expanding document access.Discovery runs continuously, not periodically. Rather than scheduling quarterly or annual scans, you maintain a current view of sensitive data across your repositories.

Governance applies once and carries through. Lake Formation tag-based policies govern findings access at the catalog level. You define your matter and confidentiality mappings once, and they carry through to every dashboard, query, and report.Audit readiness is built in. Instead of assembling reports manually before a client review or regulatory inquiry, you maintain a historical record of discovery findings and remediation actions. You can demonstrate your posture over time with consistent, structured evidence.

Security and analytics reinforce each other. Your analytics capability is built on top of your security controls, not alongside them. Strengthening one strengthens the other.

Cost considerations

The primary cost drivers for this architecture include:

  • Amazon Macie: You pay based on the number of S3 buckets evaluated and the volume of data inspected for sensitive data discovery. Review Amazon Macie pricing for current rates.
  • Amazon S3: Storage costs for both your document repositories and the compliance intelligence bucket. Consider S3 lifecycle policies to tier older findings into lower-cost storage classes.
  • AWS Glue and AWS Lake Formation: Charges for crawlers and catalog storage. For most implementations, these costs are modest.
  • Amazon QuickSight: Per-user pricing based on the edition that you select (Standard or Enterprise). Enterprise edition supports row-level and column-level security, which aligns well with matter-based governance.
  • Amazon EventBridge, AWS Security Hub, and Amazon SNS: Charges based on event volume and notifications delivered. For findings-based workflows, these costs are generally low.

Use the AWS Pricing Calculator to estimate costs based on your repository size, user count, and discovery frequency.

Getting started

Start by identifying a representative set of document repositories in Amazon S3. We recommend that you start with two or three matters that span different practice areas and confidentiality tiers.

  1. Turn on Amazon Macie for those repositories and configure automated sensitive data discovery.
  2. Catalog the findings dataset with AWS Glue and apply Lake Formation tag-based access policies aligned to your matter structure.
  3. Build your first Amazon Quick Sight dashboard to visualize findings by matter, sensitivity type, and severity.
  4. Define escalation rules in AWS Security Hub or Amazon SNS for high-severity findings.

After you validate this workflow against your initial repositories, expand gradually. Add more repositories to Macie discovery. Refine your governance tags to reflect practice areas and confidentiality tiers. Extend your dashboards from basic posture visibility to trend analysis and remediation tracking.The goal isn’t to build a comprehensive analytics solution all at once. Start with a secure foundation where discovery findings, governance, and reporting operate together in a way that aligns with your legal workflows, and then expand from there.

Conclusion

You don’t have to choose between protecting client data and understanding it. By building analytics on top of governed discovery findings and using a unified compliance workspace, you gain visibility into your data posture without weakening confidentiality boundaries.This approach brings security, governance, and analytics together in a way that reflects how legal work is actually structured. It provides continuous visibility, supports audit readiness, and delivers insight without requiring documents to move outside their system of record.

Next steps

Review the Amazon Macie User Guide to understand sensitive data discovery configuration options and Amazon Quick Sight documentation to evaluate dashboard and row-level security capabilities.

Contact your AWS account team to discuss implementation support for legal and compliance workloads.


About the authors

Photo of Author - Rohan Kamat

Rohan Kamat

Rohan Kamat is a Solutions Architecture Leader within HCLS with extensive experience in cloud architecture, cybersecurity, Identity and Access Management, and enterprise networking. Rohan focuses on helping architects build both depth in cloud technologies and strength in executive communication, making sure they can confidently guide organizations through business and technical transformation. Outside of his professional work, Rohan enjoys time with his family, organizing community cricket events, and exploring fitness and wellness activities like pickleball and ping pong. He also enjoys planning travel experiences that bring people together and create lasting shared memories.

Photo of Author- Miguel Lopez Luis

Miguel Lopez Luis

Miguel Lopez Luis is an AWS Solutions Architect who works with small and medium businesses across the United States. He graduated with a Bachelor’s degree in Cybersecurity from Bellevue University in Nebraska and is a member of the Omega Nu Lambda Honor Society. Leveraging his extensive expertise in business management, Miguel is passionate about planning strategic initiatives, leading cross-functional teams, and mentoring others. In his personal time, he enjoys activities that involve travel, sports, and cooking.

Photo of Author - Pranali Khose

Pranali Khose

Pranali Khose is an AWS Solutions Architect based in Seattle. She works directly with small and medium business (SMB) customers across the United States, to design and implement cloud solutions that address their unique business challenges and accelerate digital transformation. Pranali holds a Master of Science in Computer Science from the University of Texas at Arlington.

How to use streamlined permissions for Amazon S3 Tables and Iceberg materialized views

Post Syndicated from Srividya Parthasarathy original https://aws.amazon.com/blogs/big-data/how-to-use-streamlined-permissions-for-amazon-s3-tables-and-iceberg-materialized-views/

Apache Iceberg has emerged as the open table format for data lakes. It handles petabyte-scale datasets, lets teams evolve schemas and partitions in place, and supports time travel and incremental processing for data lake management at scale. Amazon S3 Tables provide a fully managed Apache Iceberg table experience in Amazon S3, optimized for analytics workloads, and integrate with the AWS Glue Data Catalog so AWS analytics services such as Amazon Redshift, Amazon EMR, Amazon Athena, Amazon SageMaker, and AWS Glue query your data. Together, they form the foundation of a modern data lake architecture on AWS.

S3 Tables integrate with the AWS Glue Data Catalog using AWS Identity and Access Management (IAM) – based authorization. If you manage analytics workloads across these services, you can now define permissions across storage, catalog, and compute in a single IAM policy. This gives teams already using IAM a straightforward path to govern access to S3 Tables resources without changing their existing permission model. For fine-grained access controls, you can opt in to AWS Lake Formation at any time through the AWS Management Console, AWS Command Line Interface (AWS CLI), API, or AWS CloudFormation.

Iceberg materialized views created in the Glue Data Catalog extend this foundation by letting you store pre-computed query results as Iceberg data on Amazon S3. When a query repeats aggregations or joins across large datasets, the engine reads directly from the materialized view’s S3 location rather than reprocessing the base tables. A materialized view can reside in S3 Tables or in an S3 general purpose bucket, independent of where its base tables live, which lets you place pre-computed results wherever fits your access patterns and cost model best.

In this post, we walk through how to set up and manage S3 Tables in the AWS Glue Data Catalog, create and query Iceberg materialized views, and configure access controls that work across your analytics stack with IAM-based authorization.

 Solution overview

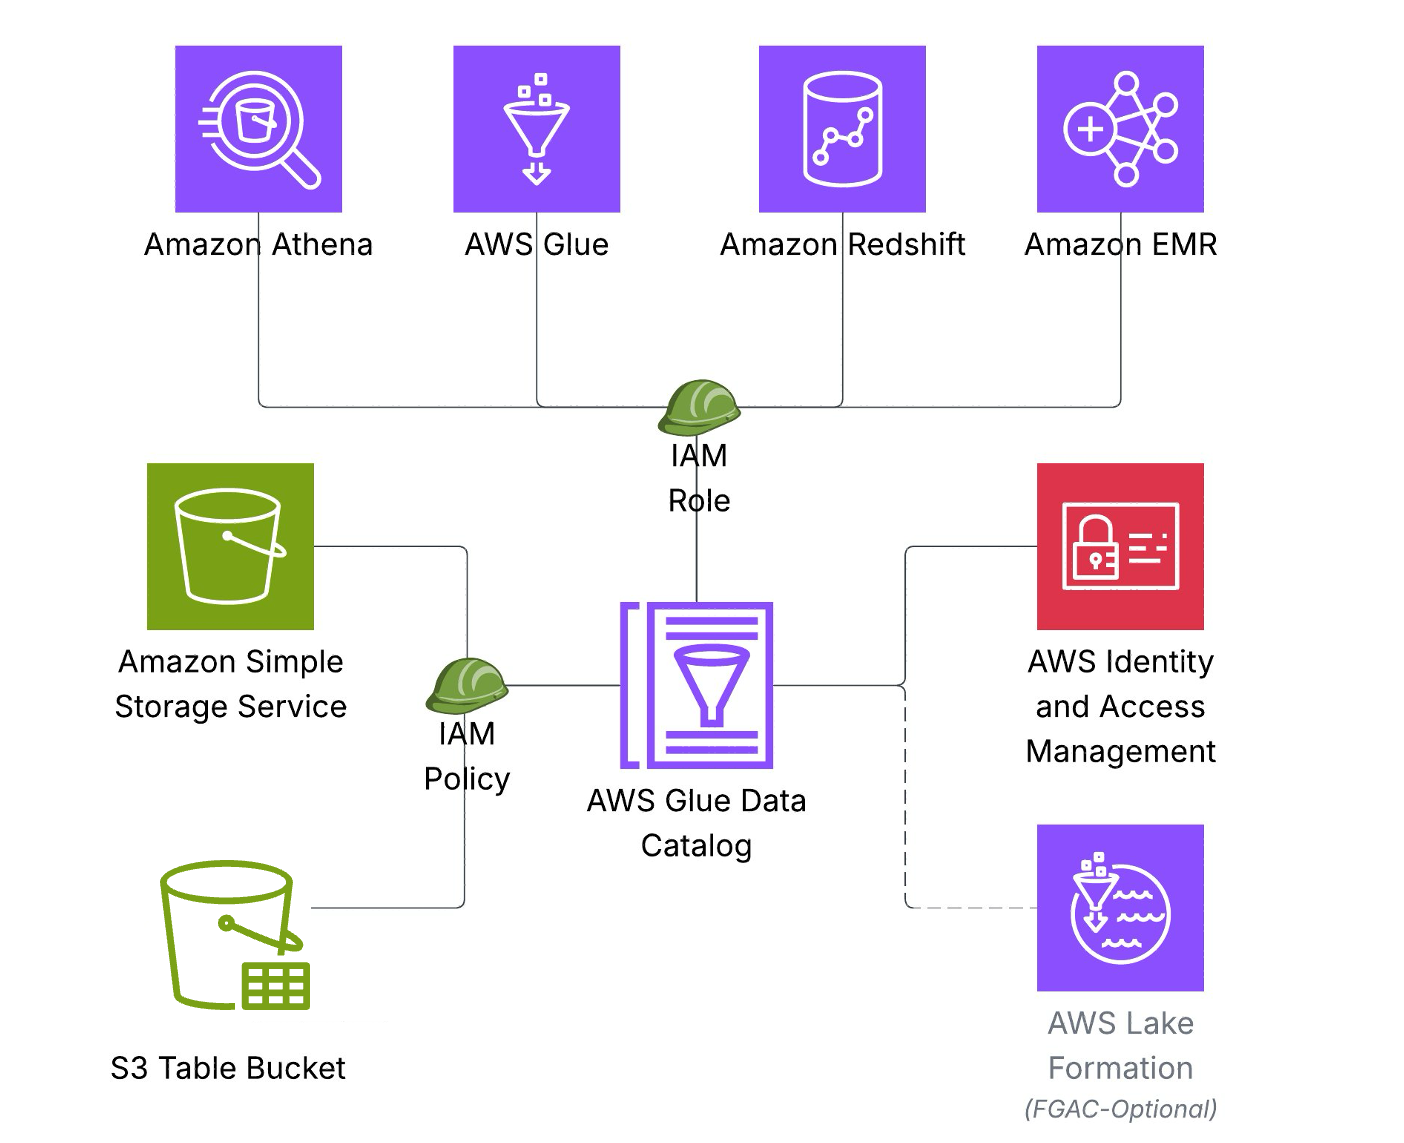
Architecture diagram showing AWS Glue Data Catalog integration with Amazon Athena, AWS Glue, Amazon Redshift, and Amazon EMR through IAM roles and policies, with Amazon S3 storage and optional AWS Lake Formation governance.

The above architecture illustrates how S3 Tables integrate with AWS Glue Data Catalog using IAM-based authorization, so you can define the necessary permissions across storage, catalog, and query engines in a single IAM policy. This permission model accelerates onboarding for new teams and workloads.

Key architecture components include:

Storage Layer: Data stored as Iceberg tables in Amazon S3 Tables

Catalog Layer: AWS Glue Data Catalog serves as the single metadata repository.

Compute Layer – Amazon Athena, AWS Glue, Amazon Redshift, and Amazon EMR connect to a single data Catalog to access Iceberg tables.

Security: AWS IAM authorizes access to resources in storage, catalog, and compute layers.

Prerequisites:

To follow along with this post, you must have an AWS account and an IAM role or user with appropriate permissions and familiarity to the following services:

  • IAM
  • AWS Glue Data Catalog
  • Amazon S3
  • Amazon Athena
  • Amazon Redshift
  • Amazon EMR

For the minimum permissions required for the role/user for metadata and data access, refer to required IAM permissions documentation.

Solution walkthrough

In this walkthrough, you will integrate S3 Tables with the AWS Glue Data Catalog, create Iceberg materialized views, and query data using multiple analytics engines. You will also learn to use materialized views when you have complex aggregations queried frequently but underlying data changes. You can follow these steps to implement the solution. It will take about 45–60 minutes to complete this walkthrough.

Setup S3 Tables and integrate with Glue Data Catalog

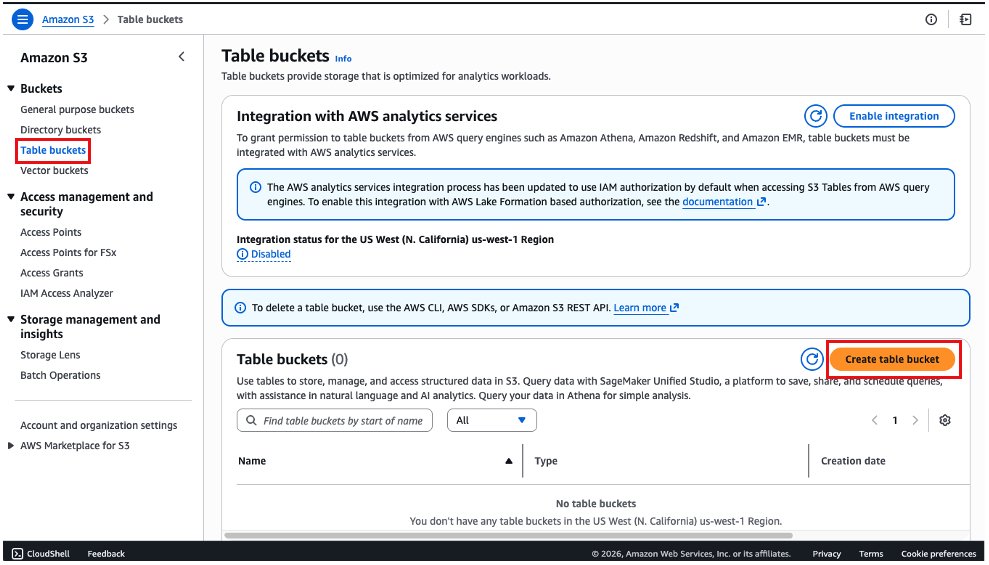
Navigate to Amazon S3 console:

  1. On the left menu, select Table buckets.
  2. Choose the Create table bucket button.

Amazon S3 console showing the Table buckets management page in the US West (N. California) us-west-1 Region with zero table buckets, integration status disabled, and the Create table bucket button highlighted.

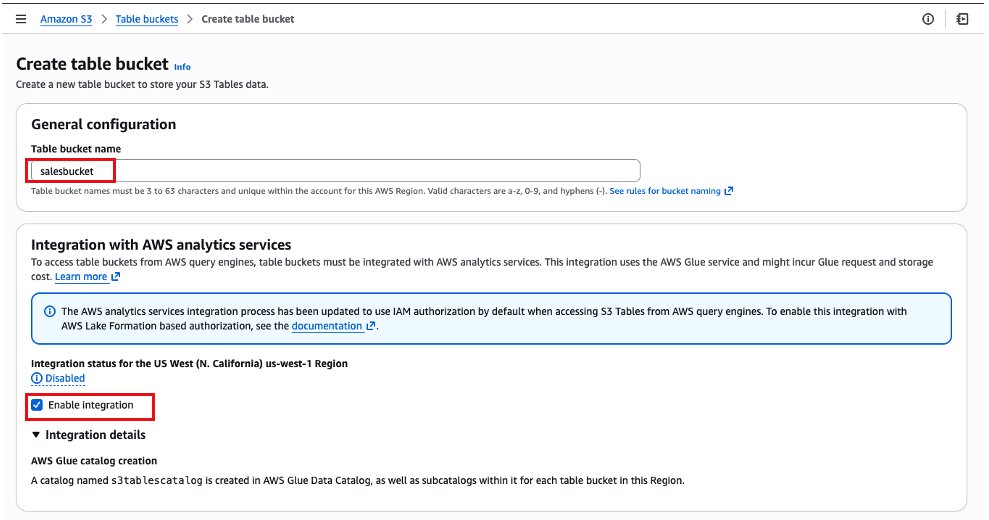
  1. In the next screen, we will fill the name of the bucket as salesbucket. Please ensure the Enable Integration configuration is checked. This step integrates S3 Tables with AWS Glue Data Catalog.

AWS S3 Create table bucket form with General configuration showing bucket name "salesbucket" and Integration with AWS analytics services section with Enable integration checkbox selected.

  1. Keep the other options as default and choose Create table bucket.
  2. After it is created, you will be redirected back to the list of table buckets. Choose the table bucket salesbucket.
  3. Select the Create table with Athena button.
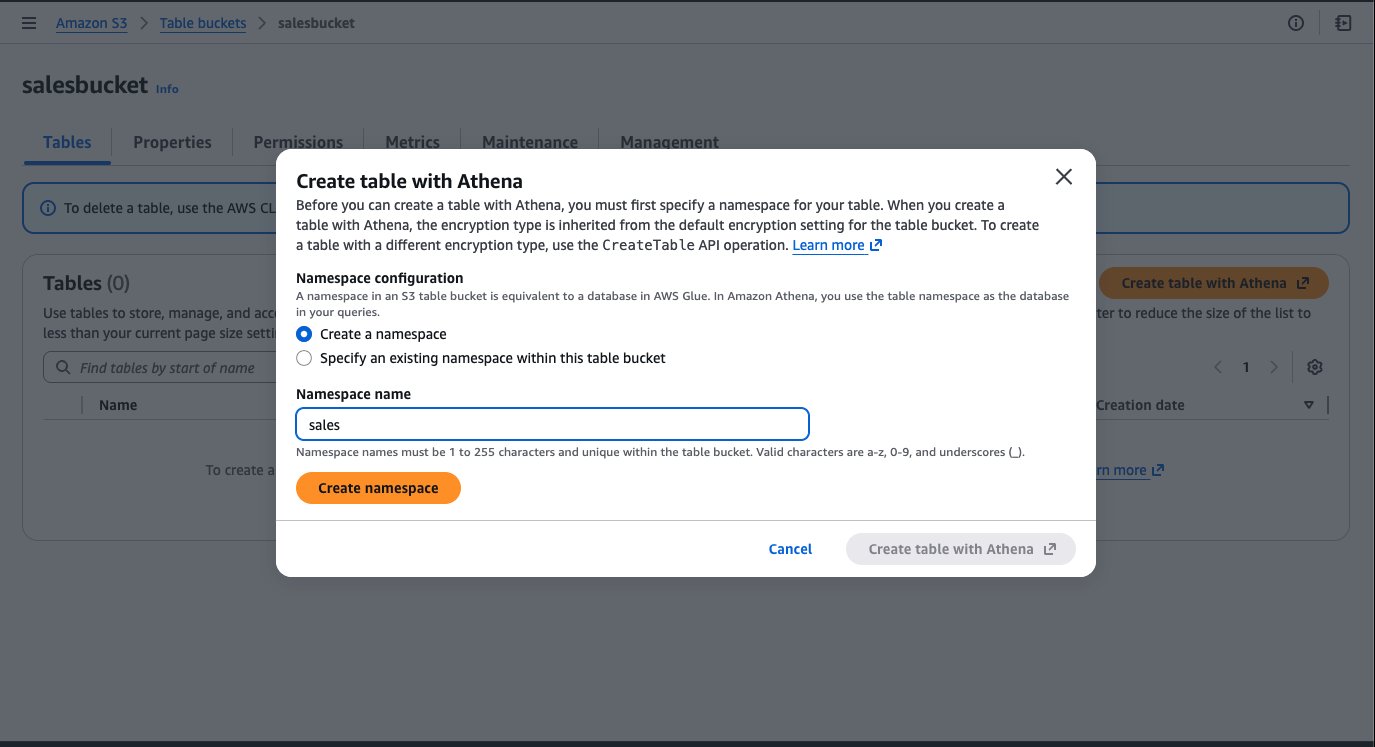
  4. Create a namespace in S3 Tables which is equivalent to a database in AWS Glue Data Catalog. Enter namespace (database) name as “sales” and click Create namespace.

Create table with Athena dialog in the Amazon S3 salesbucket console showing namespace configuration with "Create a namespace" selected and namespace name set to "sales."

  1. Choose Create table with Athena, and a new tab will be open with the Amazon Athena console.
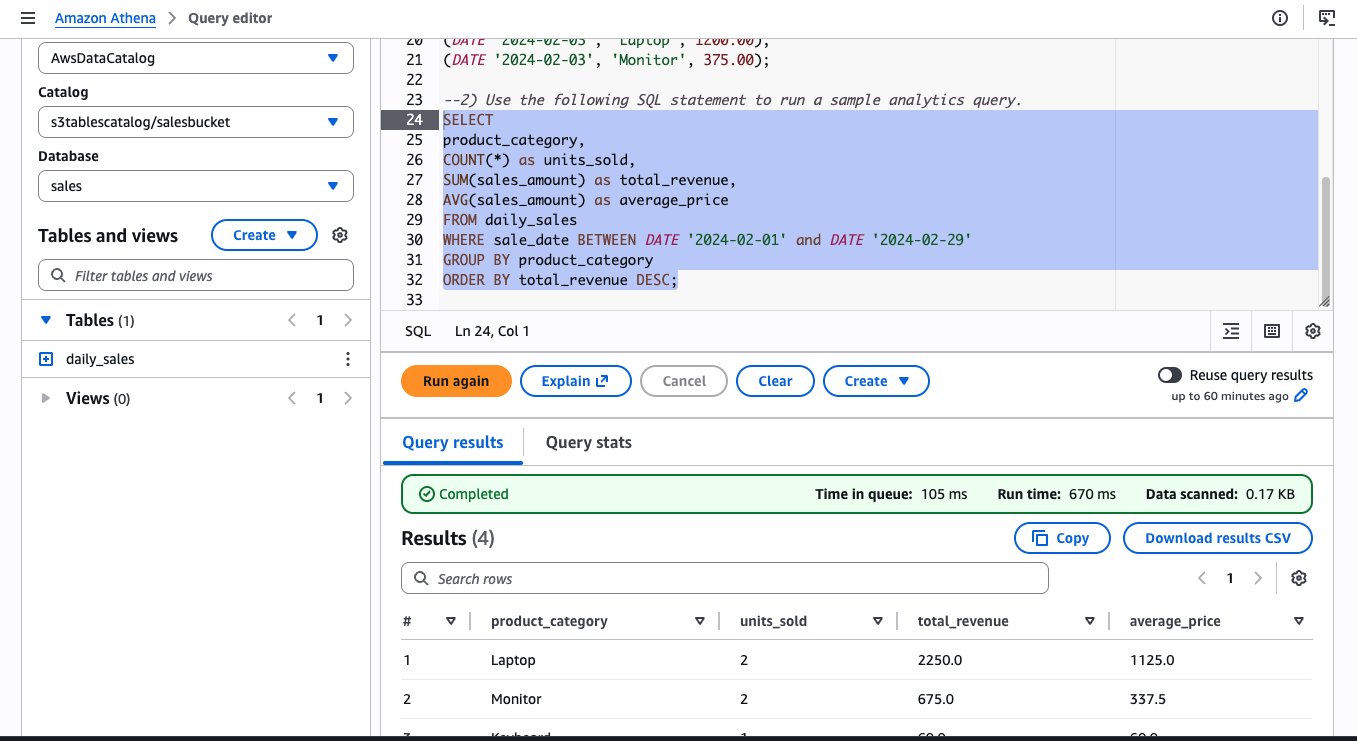
  2. When the Amazon Athena console opens, you will see an example of a query to create a table and examples to insert rows in that table. You could use this query block by uncommenting the code and executing each statement individually by highlighting it. At the end, you will have data in the table.

Amazon Athena query editor showing a SQL analytics query on the daily_sales table with results displaying product categories, units sold, total revenue, and average price for February 2024 sales data.

Query S3 Tables and create materialized view using Amazon EMR:

To run the instruction on Amazon EMR, complete the following steps to configure the cluster:

  1. Create an IAM role for the Amazon EMR instance profile following the Amazon EMR Management Guide. Add the following as policies and trust relationship for working on materialized views.

Replace ACCOUNT_ID with your AWS account ID, Instance_profile_role to the Amazon EMR instance profile role, and REGION with your AWS Region.

{
   "Version":"2012-10-17",
   "Statement":[
      {
         "Sid":"GlueDataCatalogPermissions",
         "Effect":"Allow",
         "Action":[
            "glue:GetCatalog",
            "glue:GetDatabase",
            "glue:CreateTable",
            "glue:GetTable",
            "glue:GetTables",
            "glue:UpdateTable",
            "glue:DeleteTable"
         ],
         "Resource":[
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:catalog",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:catalog/s3tablescatalog",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:catalog/s3tablescatalog/*",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:database/salesdb",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:database/salesdb/*",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:database/s3tablescatalog",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:database/s3tablescatalog/*",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:table/s3tablescatalog/*",
            "arn:aws:glue:<REGION>:<ACCOUNT ID>:table/*/*"
         ]
      },
      {
         "Sid":"S3TablesDataAccessPermissions",
         "Effect":"Allow",
         "Action":[
            "s3tables:GetTableBucket",
            "s3tables:GetNamespace",
            "s3tables:GetTable",
            "s3tables:GetTableMetadataLocation",
            "s3tables:GetTableData",
            "s3tables:ListTableBuckets",
            "s3tables:CreateTable",
            "s3tables:PutTableData",
            "s3tables:UpdateTableMetadataLocation",
            "s3tables:ListNamespaces",
            "s3tables:ListTables",
            "s3tables:DeleteTable"
         ],
         "Resource":[
            "arn:aws:s3tables:<REGION>:<ACCOUNT ID>:bucket/*"
         ]
      },
      {
         "Effect":"Allow",
         "Action":"iam:PassRole",
         "Resource":"arn:aws:iam::<ACCOUNT ID>:role/service-role/<Instance_profile_role>"
      }
   ]
}

Add the following to the trust policy in addition to existing:

 {
            "Sid": "",
            "Effect": "Allow",
            "Principal": {
                "Service": "glue.amazonaws.com"
            },
            "Action": "sts:AssumeRole"
        }
  1. Launch an Amazon EMR cluster 7.12.0 or higher with instance profile role created in the previous step and with Iceberg enabled. For more information, refer to Use an Iceberg cluster with Spark.
  2. Connect to the primary node of your Amazon EMR cluster by using SSH, and run the following command to start a Spark application with the required configurations:

Replace bucket_name with your bucket name.

spark-sql \
  --conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions \
  --conf spark.sql.catalog.glue_catalog=org.apache.iceberg.spark.SparkCatalog \
  --conf spark.sql.catalog.glue_catalog.type=glue \
  --conf spark.sql.catalog.glue_catalog.warehouse=s3://<bucket_name> \
  --conf spark.sql.catalog.glue_catalog.glue.region=<region> \
  --conf spark.sql.catalog.glue_catalog.glue.id=<accountid>:s3tablescatalog/salesbucket \
  --conf spark.sql.catalog.glue_catalog.glue.account-id=<accountid> \
  --conf spark.sql.catalog.glue_catalog.client.region=<region> \
  --conf spark.sql.optimizer.answerQueriesWithMVs.enabled=true \
  --conf spark.sql.defaultCatalog=glue_catalog
  1. Run the following queries to query the daily_sales table.
spark-sql ()> use sales;
spark-sql (sales)> select * from daily_sales;
2024-01-15 Laptop 900.0
2024-01-15 Monitor 250.0
2024-01-16 Laptop 1350.0
2024-02-01 Monitor 300.0
2024-02-01 Keyboard 60.0
2024-02-02 Mouse 25.0
2024-02-02 Laptop 1050.0
2024-02-03 Laptop 1200.0
2024-02-03 Monitor 375.0
  1. Create Materialized view.
CREATE MATERIALIZED VIEW sales_mv as 
SELECT 
    product_category,
    COUNT(*) as units_sold,
    SUM(sales_amount) as total_revenue, 
    AVG(sales_amount) as average_price 
FROM 
    glue_catalog.sales.daily_sales 
GROUP BY 
    product_category;

A newly created materialized view is populated with the initial query results but does not update automatically as base table data changes. To keep it current, specify a REFRESH EVERY clause when creating the view. This accepts a time interval and unit, so you can define how often the materialized view is recomputed from the base tables.

  1. Add refresh interval.
CREATE MATERIALIZED VIEW sales_mv 
SCHEDULE REFRESH EVERY 2 HOURS as 
SELECT 
    product_category,
    COUNT(*) as units_sold,
    SUM(sales_amount) as total_revenue, 
    AVG(sales_amount) as average_price 
FROM 
    glue_catalog.sales.daily_sales 
GROUP BY 
    product_category;
  1. Alternatively, you can refresh them manually.

For manual full refresh, you can use the following command:

REFRESH MATERIALIZED VIEW sales_mv FULL;

For manual incremental refresh, you can use the following command:

REFRESH MATERIALIZED VIEW sales_mv;

For more details, refer to Refreshing materialized views.

  1. Query the MV.
spark-sql (sales)> select * from sales_mv
Keyboard 1 60.0 60.0
Laptop 4 4500.0 1125.0
Mouse 1 25.0 25.0
Monitor 3 925.0 308.3333333333333

After the Iceberg materialized views are created, you can access them using IAM principals that have required IAM permissions to Glue Data Catalog resource and its underlying storage.

Iceberg materialized views are flexible in how they combine base tables and access control modes. Base tables can reside in S3 general-purpose buckets (with IAM or Lake Formation access control), in S3 Tables (through the s3tablescatalog catalog), or a combination of these—all within a single materialized view definition. The materialized view itself can use either IAM or AWS Lake Formation access control, independently of its base tables.

For more details, refer to How materialized views work with AWS Glue.

Query using Athena:

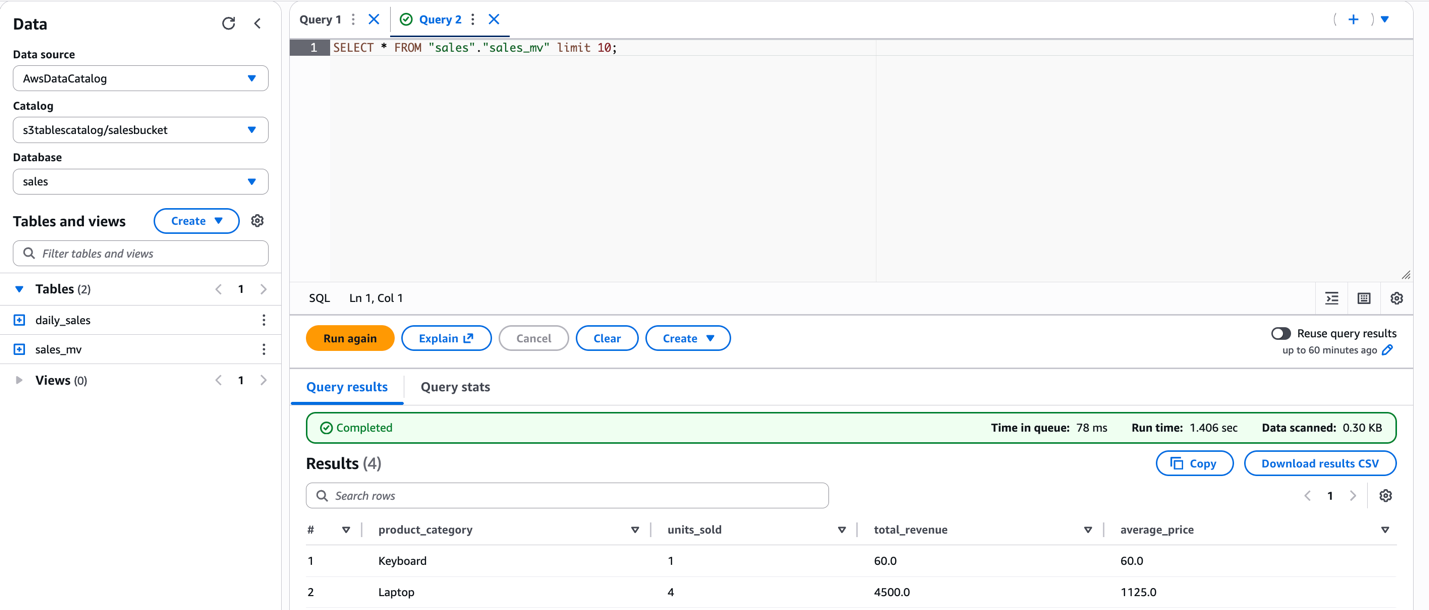
Additionally, you can query the same materialized view from Athena SQL. The following image shows the same query run on Athena and the resulting output.Amazon Athena query editor showing SELECT query results from the sales_mv materialized view with product category aggregations including Keyboard and Laptop sales data.

Query using Amazon Redshift:

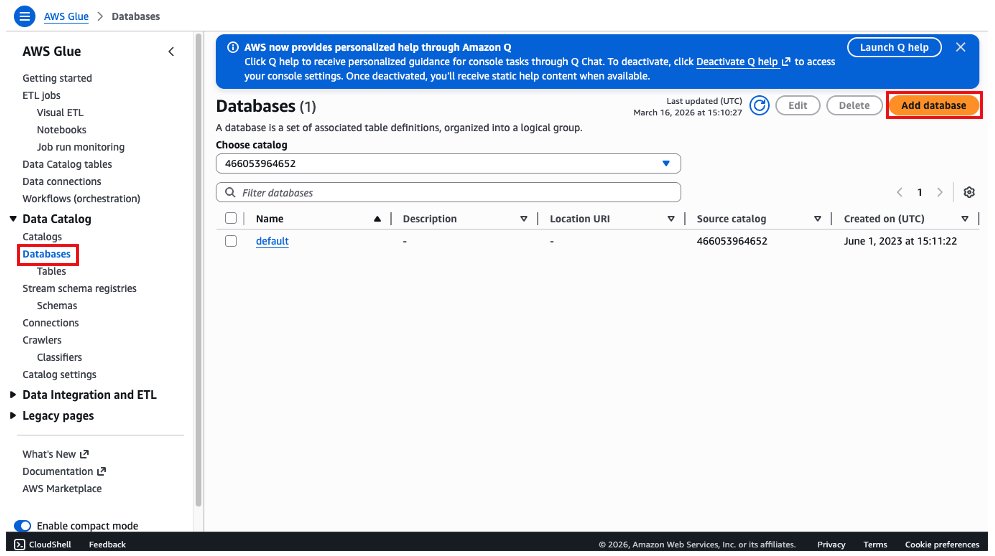
To query the S3 Tables in AWS Glue Data Catalog using Amazon Redshift, you must create a database in the default catalog in Glue Data Catalog that points to the S3 Tables catalog.

  1. On the AWS Glue console, choose Databases, and then choose Add Database.

AWS Glue Data Catalog Databases page showing one default database in catalog 466053964652, with the Add database button highlighted.

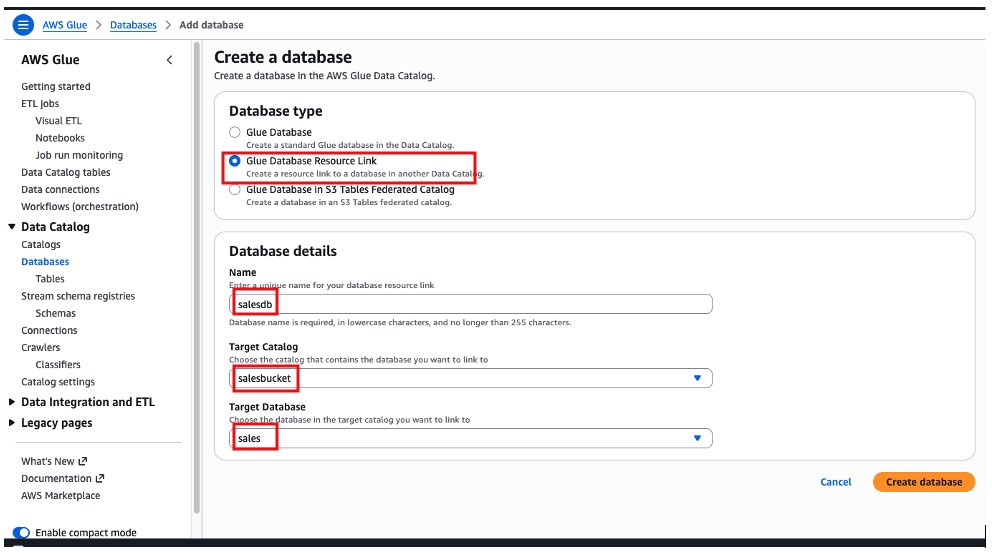
  1. Choose the Glue Database resource link option, add a name for the database, choose salesbucket on the target catalog and sales as the target database. Then select Create database.

AWS Glue Create a database form with Glue Database Resource Link selected, name set to "salesdb," target catalog "salesbucket," and target database "sales."

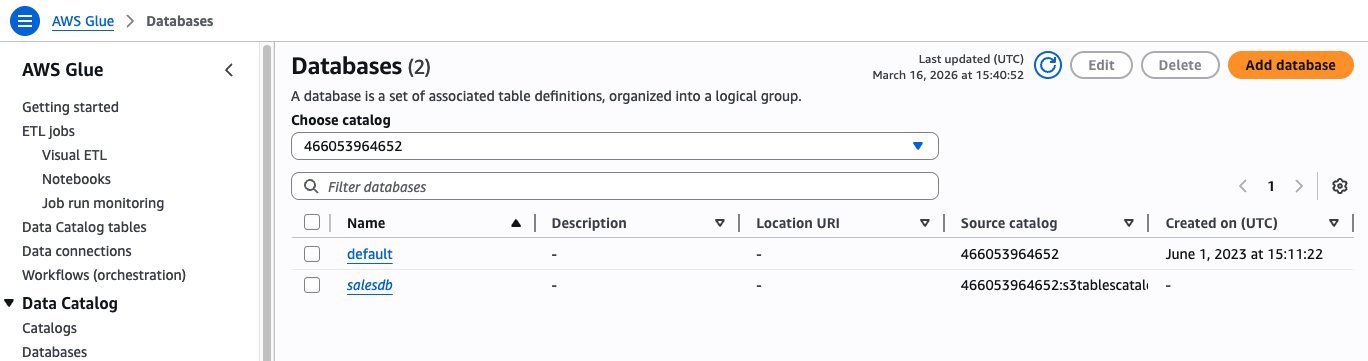
After creating the database, we will see the “salesdb” resource link under Databases on AWS Glue Data Catalog.

AWS Glue Data Catalog Databases page showing two databases: "default" and the newly created "salesdb" resource link with source catalog pointing to s3tablescatalog.

Create IAM role with the following policy for the Amazon Redshift schema creation. Replace the AWS Region and account ID for your account.

{
   "Version":"2012-10-17",
   "Statement":[
      {
         "Sid":"GlueDataCatalogPermissions",
         "Effect":"Allow",
         "Action":[
            "glue:GetCatalog",
            "glue:GetDatabase",
            "glue:CreateTable",
            "glue:GetTable",
            "glue:GetTables",
            "glue:UpdateTable",
            "glue:DeleteTable"
         ],
         "Resource":[
            "arn:aws:glue:<REGION>:<ACCOUNTID>:catalog",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:catalog/s3tablescatalog",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:catalog/s3tablescatalog/*",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:database/salesdb",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:database/salesdb/*",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:database/s3tablescatalog",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:database/s3tablescatalog/*",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:table/s3tablescatalog/*",
            "arn:aws:glue:<REGION>:<ACCOUNTID>:table/*/*"
         ]
      },
      {
         "Sid":"S3TablesDataAccessPermissions",
         "Effect":"Allow",
         "Action":[
            "s3tables:GetTableBucket",
            "s3tables:GetNamespace",
            "s3tables:GetTable",
            "s3tables:GetTableMetadataLocation",
            "s3tables:GetTableData",
            "s3tables:ListTableBuckets",
            "s3tables:CreateTable",
            "s3tables:PutTableData",
            "s3tables:UpdateTableMetadataLocation",
            "s3tables:ListNamespaces",
            "s3tables:ListTables",
            "s3tables:DeleteTable"
         ],
         "Resource":[
            "arn:aws:s3tables:<REGION>:<ACCOUNTID>:bucket/*"
         ]
      }
   ]
}

Create an Amazon Redshift provisioned cluster or Amazon Redshift Serverless, attaching the IAM role created in previous step.

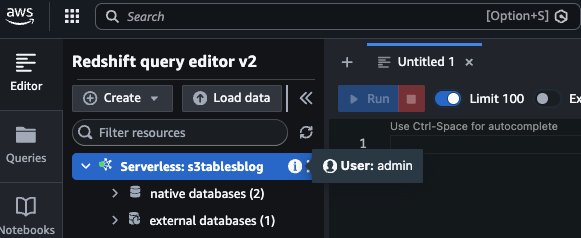
To access the AWS Glue Catalog and the resource link, you can now log in to Amazon Redshift as a local user. We use the admin user and Amazon Redshift Query Editor v2.

Amazon Redshift Query Editor v2 interface connected to Serverless workgroup "s3tablesblog" showing 2 native databases and 1 external database with an empty query editor ready for input.

To create the external schema, you must run the following command: Replace ACCOUNT_ID with your AWS Account ID, IAM_ROLE to IAM role created for schema access, and REGION with your AWS Region.

CREATE EXTERNAL SCHEMA salesdb
FROM DATA CATALOG DATABASE 'salesdb'
IAM_ROLE 'arn:aws:iam::<ACCOUNT_ID>:role/<IAM_ROLE>'
REGION '<REGION>'
CATALOG_ID '<ACCOUNT_ID>';

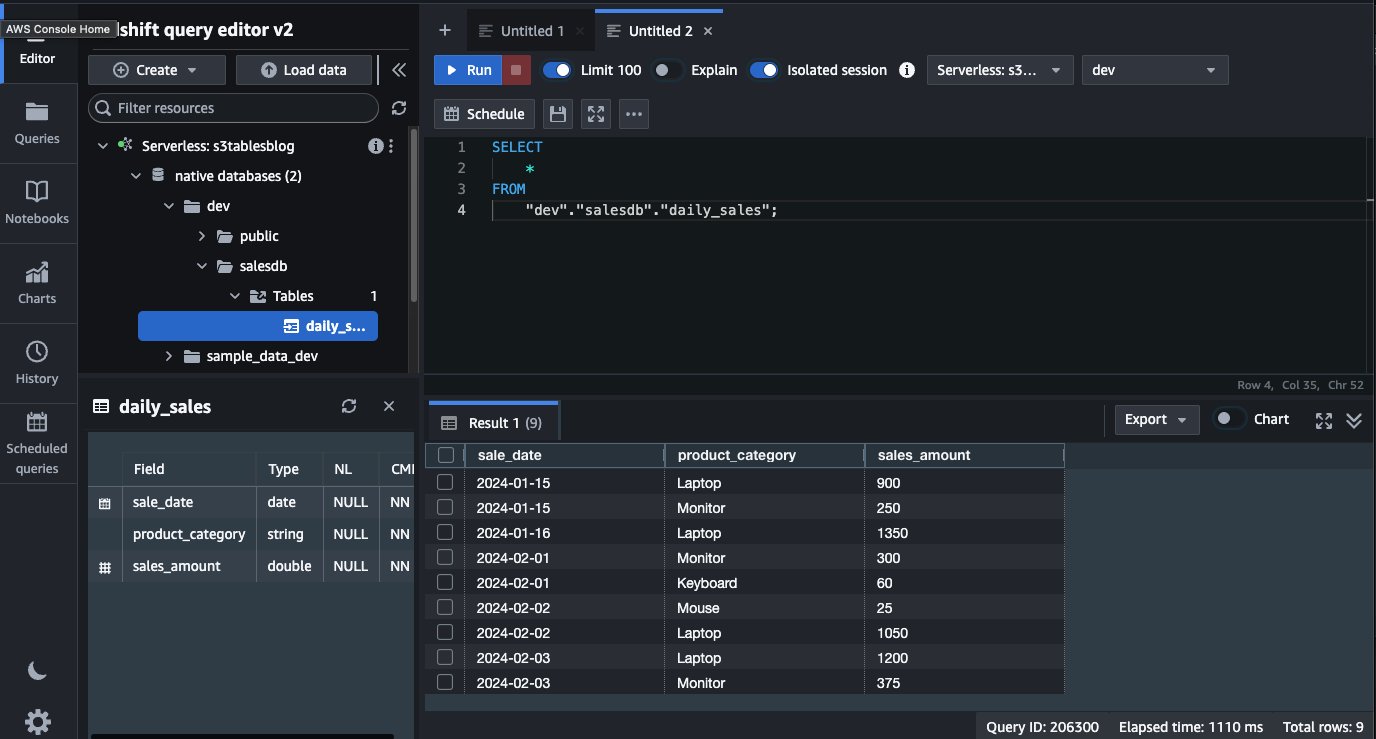
After you have created the external schema, it will show up on the left side, under the dev database. The table that we created, daily_sales, is available and we can query directly from Amazon Redshift using a local user.

Amazon Redshift Query Editor v2 showing a SELECT query on the daily_sales table in the salesdb schema with 9 rows of results displaying sale dates, product categories, and sales amounts from January–February 2024.

Cleanup:

After completing the walkthrough, follow these steps to remove the resources and avoid ongoing charges. These cleanup steps will permanently delete the data, including the daily_sales table and sales_mv materialized view. Make sure that you have backed up the data that you need to retain before proceeding.

To avoid incurring future charges, clean up the resources that you created during this walkthrough:

  • Remove the Glue Data Catalog resources
  • Delete the table bucket
  • Terminate and Delete the Amazon Redshift cluster
  • Terminate and Delete the Amazon EMR cluster
  • Delete the IAM roles/policies created

Conclusion

Amazon S3 Tables now integrate with AWS Glue Data Catalog through IAM-based authorization via a single IAM policy. By consolidating permissions for storage, catalog, and query engines into one IAM policy, you can streamline authorization with AWS analytics services like Amazon Athena, Amazon EMR, and AWS Glue. You can use this streamlined IAM authorization model to build your data lake faster while maintaining enterprise-grade security. For organizations with additionally granular data access requirements, AWS Lake Formation remains available to layer fine-grained access controls on top of this foundation. This is configurable through the AWS Management Console, CLI, API, or CloudFormation. This integration allows AWS analytics users to use IAM and scale their analytics capabilities with reduced operational complexity.

To learn more about to S3 Tables and integration with Glue Data catalog, visit: Amazon S3 Tables integration with AWS analytics services overview and Integrating with Amazon S3 Tables.


About the authors

Ricardo Serafim

Ricardo is a Senior Analytics Specialist Solutions Architect at AWS. He has been helping companies with Data Warehouse solutions since 2007.

Milind Oke

Milind is a Data Warehouse Specialist Solutions Architect based out of New York. He has been building data warehouse solutions for over 15 years and specializes in Amazon Redshift.

Pratik Das

Pratik is a Senior Product Manager with AWS Lake Formation. He is passionate about all things data and works with customers to understand their requirements and build delightful experiences. He has a background in building data-driven solutions and machine learning systems.

Srividya Parthasarathy

Srividya is a Senior Big Data Architect on the AWS Lake Formation team. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.

Improve DynamoDB analytics with AWS Glue zero-ETL schema and partition controls

Post Syndicated from Raju Ansari original https://aws.amazon.com/blogs/big-data/improve-dynamodb-analytics-with-aws-glue-zero-etl-schema-and-partition-controls/

You store transactional data in Amazon DynamoDB and get single-digit millisecond performance. However, when you want to run analytics, machine learning (ML), or reporting on that same data, you face a gap: your flexible, semi-structured DynamoDB schemas don’t align with the flat, columnar formats that analytics engines require. Bridging this gap typically means building and maintaining custom ETL pipelines, which adds development cost and operational overhead.

AWS Glue Zero-ETL integration removes that pipeline work. It enables replication of your DynamoDB tables to Apache Iceberg tables in Amazon Simple Storage Service (Amazon S3), then query it directly with Amazon Athena. During setup, you can configure two capabilities that will shape how replicated data looks and performs: schema unnesting flattens nested attributes into individual columns, and data partitioning organizes data so your queries scan only what they need.

In this post, you learn how to replicate Amazon DynamoDB data to Apache Iceberg tables in Amazon S3 through a zero-ETL integration. We walk through the challenges that the DynamoDB nested, schema-flexible data model introduces for analytics workloads, and show you how to configure schema unnesting and data partitioning for a sample product catalog table. We also cover how to query the replicated data in Amazon Athena using standard SQL.

Semi-structured data meets analytics

Your product catalog in DynamoDB contains items with nested attributes like product details, pricing tiers, and inventory information. A typical item looks like this:

{
  "product_id": "P-1001",
  "name": "Wireless Headphones",
  "productdetails": {
    "brand": "AudioTech",
    "category": "Electronics",
    "weight_kg": 0.25,
    "specification": {
       "color": "Black",
       "storage": "128GB"
    }
  },
  "pricing": {
    "list_price": 79.99,
    "discount_pct": 10
  },
  "created_at": 1701388800000
}

This structure supports fast transactional reads and writes. However, when you replicate this data for analytics, you face two decisions:

  • You must decide whether to flatten nested maps like productdetails into individual columns or preserve them as-is.
  • You must choose how to organize the data on disk so that queries filtering by brand or date range scan only relevant partitions.

With AWS Glue Zero-ETL, you address both decisions through configurable schema unnesting and data partitioning.

Solution overview

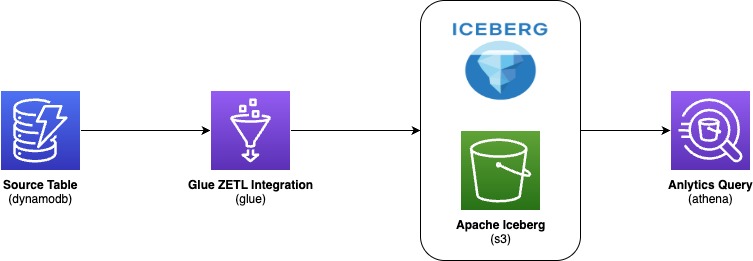
You replicate data from your DynamoDB table through AWS Glue Zero-ETL into Apache Iceberg tables stored in Amazon S3, then query the results with Amazon Athena. The following diagram illustrates the end-to-end architecture:

Data flow diagram showing AWS data pipeline: DynamoDB source table → AWS Glue zero-ETL integration → Apache Iceberg on Amazon S3 → Amazon Athena analytics query.

AWS Glue zero-ETL ingests data from Amazon DynamoDB, writes it in Apache Iceberg format to your Amazon S3 data lake, and makes it available for SQL queries in Amazon Athena—with no pipelines to build or maintain. With this integration, you:

  • Save development time by skipping custom code and ETL job management
  • Keep DynamoDB performance intact because replication doesn’t consume table’s provisioned read/write capacity
  • Get data within 15 minutes of changes in the source table
  • Query with standard tools because data lands in Apache Iceberg format, an open table format that AWS natively supports for high-performance analytics

During setup, you configure two output settings:

  1. Schema unnesting in Zero-ETL: You choose how nested attributes appear in the target. Flattening nested maps into individual columns streamlines your queries and reduces complexity.
  2. Data partitioning in Zero-ETL: You choose how data is organized into partitions. When you filter on a partition column, the query engine reads only matching data instead of scanning everything, cutting both query time and cost.

Schema unnesting

When you create a zero-ETL integration, you can choose one of three unnesting options. Schema unnesting transforms complex, nested DynamoDB structures into formats that analytics engines can query directly, removing post-processing transformations.

Each option changes how nested DynamoDB attributes appear in the target table. The right choice depends on your analytics tools and how consistent your DynamoDB schemas are.

Option 1: No unnesting

This option preserves the original nested structure. DynamoDB maps and lists remain as structured columns in the target.

Using the product example, the target table retains productid and value as columns to hold DynamoDB partition key and a DynamoDB record respectively.

Recommended for: Workloads where your analytics tools natively support querying nested data and you want to preserve the DynamoDB structure unchanged.

Option 2: Unnest one level

This option flattens top-level maps into individual columns. Lists remain nested.

With this option, productdetails and pricing each become separate columns.

Recommended for: Scenarios where your DynamoDB items have a consistent schema and you want to balance structure preservation with query simplicity.

Option 3: Unnest all levels (default)

This option recursively flattens nested structures using dot notation and produces the flattest schema.

For the product table, this creates columns such as productdetails.brand, productdetails.category, productdetails.specification.color , productdetails.specification.storage , pricing.list_price, and pricing.discount_pct. The pricing map flattens similarly. Each column is directly queryable without nested access patterns.

Recommended for: Analytics tools that prefer flat schemas when your DynamoDB items have a reasonably consistent structure. Note that deeply nested or highly variable schemas can produce very wide tables.

Data partitioning

You can speed up your queries and reduce costs by partitioning your replicated data. Partitioning divides data into logical segments on disk.

When you include a filter on a partition column in your query, the query engine skips irrelevant segments entirely. This behavior is called partition pruning: instead of scanning the entire dataset, the engine reads only the data that matches your filter conditions. For large tables, partition pruning can reduce both query runtime and cost significantly.

Default partitioning

If you don’t specify partition columns, AWS Glue Zero-ETL partitions data using the DynamoDB primary key with bucketing. This approach supports general-purpose queries without requiring manual configuration. For specific query patterns or performance requirements, you can define custom partitioning strategies described in the subsections that follow.

Identity partitioning

Identity partitioning uses raw column values to create partitions. You apply this strategy to low-to-medium cardinality columns such as brand, category, or AWS Region. To partition the product table by productdetails.brand and create a separate partition for each brand, use this configuration:

{
  "partitionSpec": [
    {
      "fieldName": "productdetails.brand",
      "functionSpec": "identity"
    }
  ]
}

With this setup, AWS Glue creates one partition directory per unique brand value. When you query for a specific brand, Athena reads only that partition.

Important: Avoid identity partitioning on high-cardinality columns such as primary keys or timestamps. This creates many small partitions, which degrades both ingestion and query performance

Time-based partitioning

Time-based partitioning organizes data by timestamp at a chosen granularity: year, month, day, or hour. You apply this strategy to time-series data and time-range queries. To partition the product table by month on the created_at column, which stores epoch milliseconds, use this configuration:

{
  "partitionSpec": [
    {
      "fieldName": "created_at",
      "functionSpec": "month",
      "conversionSpec": "epoch_milli"
    }
  ]
}

The conversionSpec parameter tells AWS Glue how to interpret the source timestamp. Supported values: epoch_sec (Unix seconds), epoch_milli (Unix milliseconds), and iso (ISO 8601 format).

Note: The original column values remain unchanged. AWS Glue transforms only the partition column values to timestamp type in the target table

Multi-level partitioning

You can combine strategies for a hierarchical scheme. To partition first by month and then by brand, use this configuration:

{
  "partitionSpec": [
    {
      "fieldName": "created_at",
      "functionSpec": "month",
      "conversionSpec": "epoch_milli"
    },
    {
      "fieldName": "productdetails.brand",
      "functionSpec": "identity"
    }
  ]
}

This scheme supports efficient queries that filter by date range, brand, or both. Place higher-selectivity columns first in the hierarchy and align the scheme with your most common query patterns.

Best practices

Keep these guidelines in mind when you configure your integration:

  • Avoid identity partitioning on high-cardinality columns such as primary keys, timestamps, or system-generated IDs. This leads to partition explosion and degrades performance.
  • Apply only one time-based function per column. For example, don’t partition col1 by year, month, day, and hour simultaneously.
  • Match conversionSpec to your actual data format. If your timestamps are in epoch milliseconds, use epoch_milli, not epoch_sec or iso.
  • Choose granularity based on data volume. High-volume tables benefit from finer granularity (day or hour). Lower-volume tables work well with coarser granularity (month or year).
  • Account for timezone implications with ISO timestamps. AWS Glue Zero-ETL normalizes timestamp partition values to UTC.

Prerequisites

To implement the AWS Glue Zero-ETL integration with a DynamoDB source, you will need:

  1. An AWS account with least privilege principle
  2. An AWS Glue database (for example, ddb_zero_etl_demo_db) with an Amazon S3 bucket associated as the database location (setup instructions)
  3. AWS Glue Data Catalog settings updated with an AWS Identity and Access Management (IAM) policy that grants fine-grained access control for zero-ETL (setup instructions)
  4. Create an IAM role named zetl-role, to be used by zero-ETL to access data from your DynamoDB table
  5. A DynamoDB source table (for example, product) configured for zero-ETL integration (setup instructions)

Walkthrough: Create the zero-ETL integration

Complete these steps to create a zero-ETL integration with DynamoDB as the source and Apache Iceberg tables in Amazon S3 as the target.

Step 1: Select the source type

  1. Open the AWS Glue console.
  2. In the navigation pane, under Data Integration and ETL, choose Zero-ETL integrations.
  3. Choose Create zero-ETL integration.
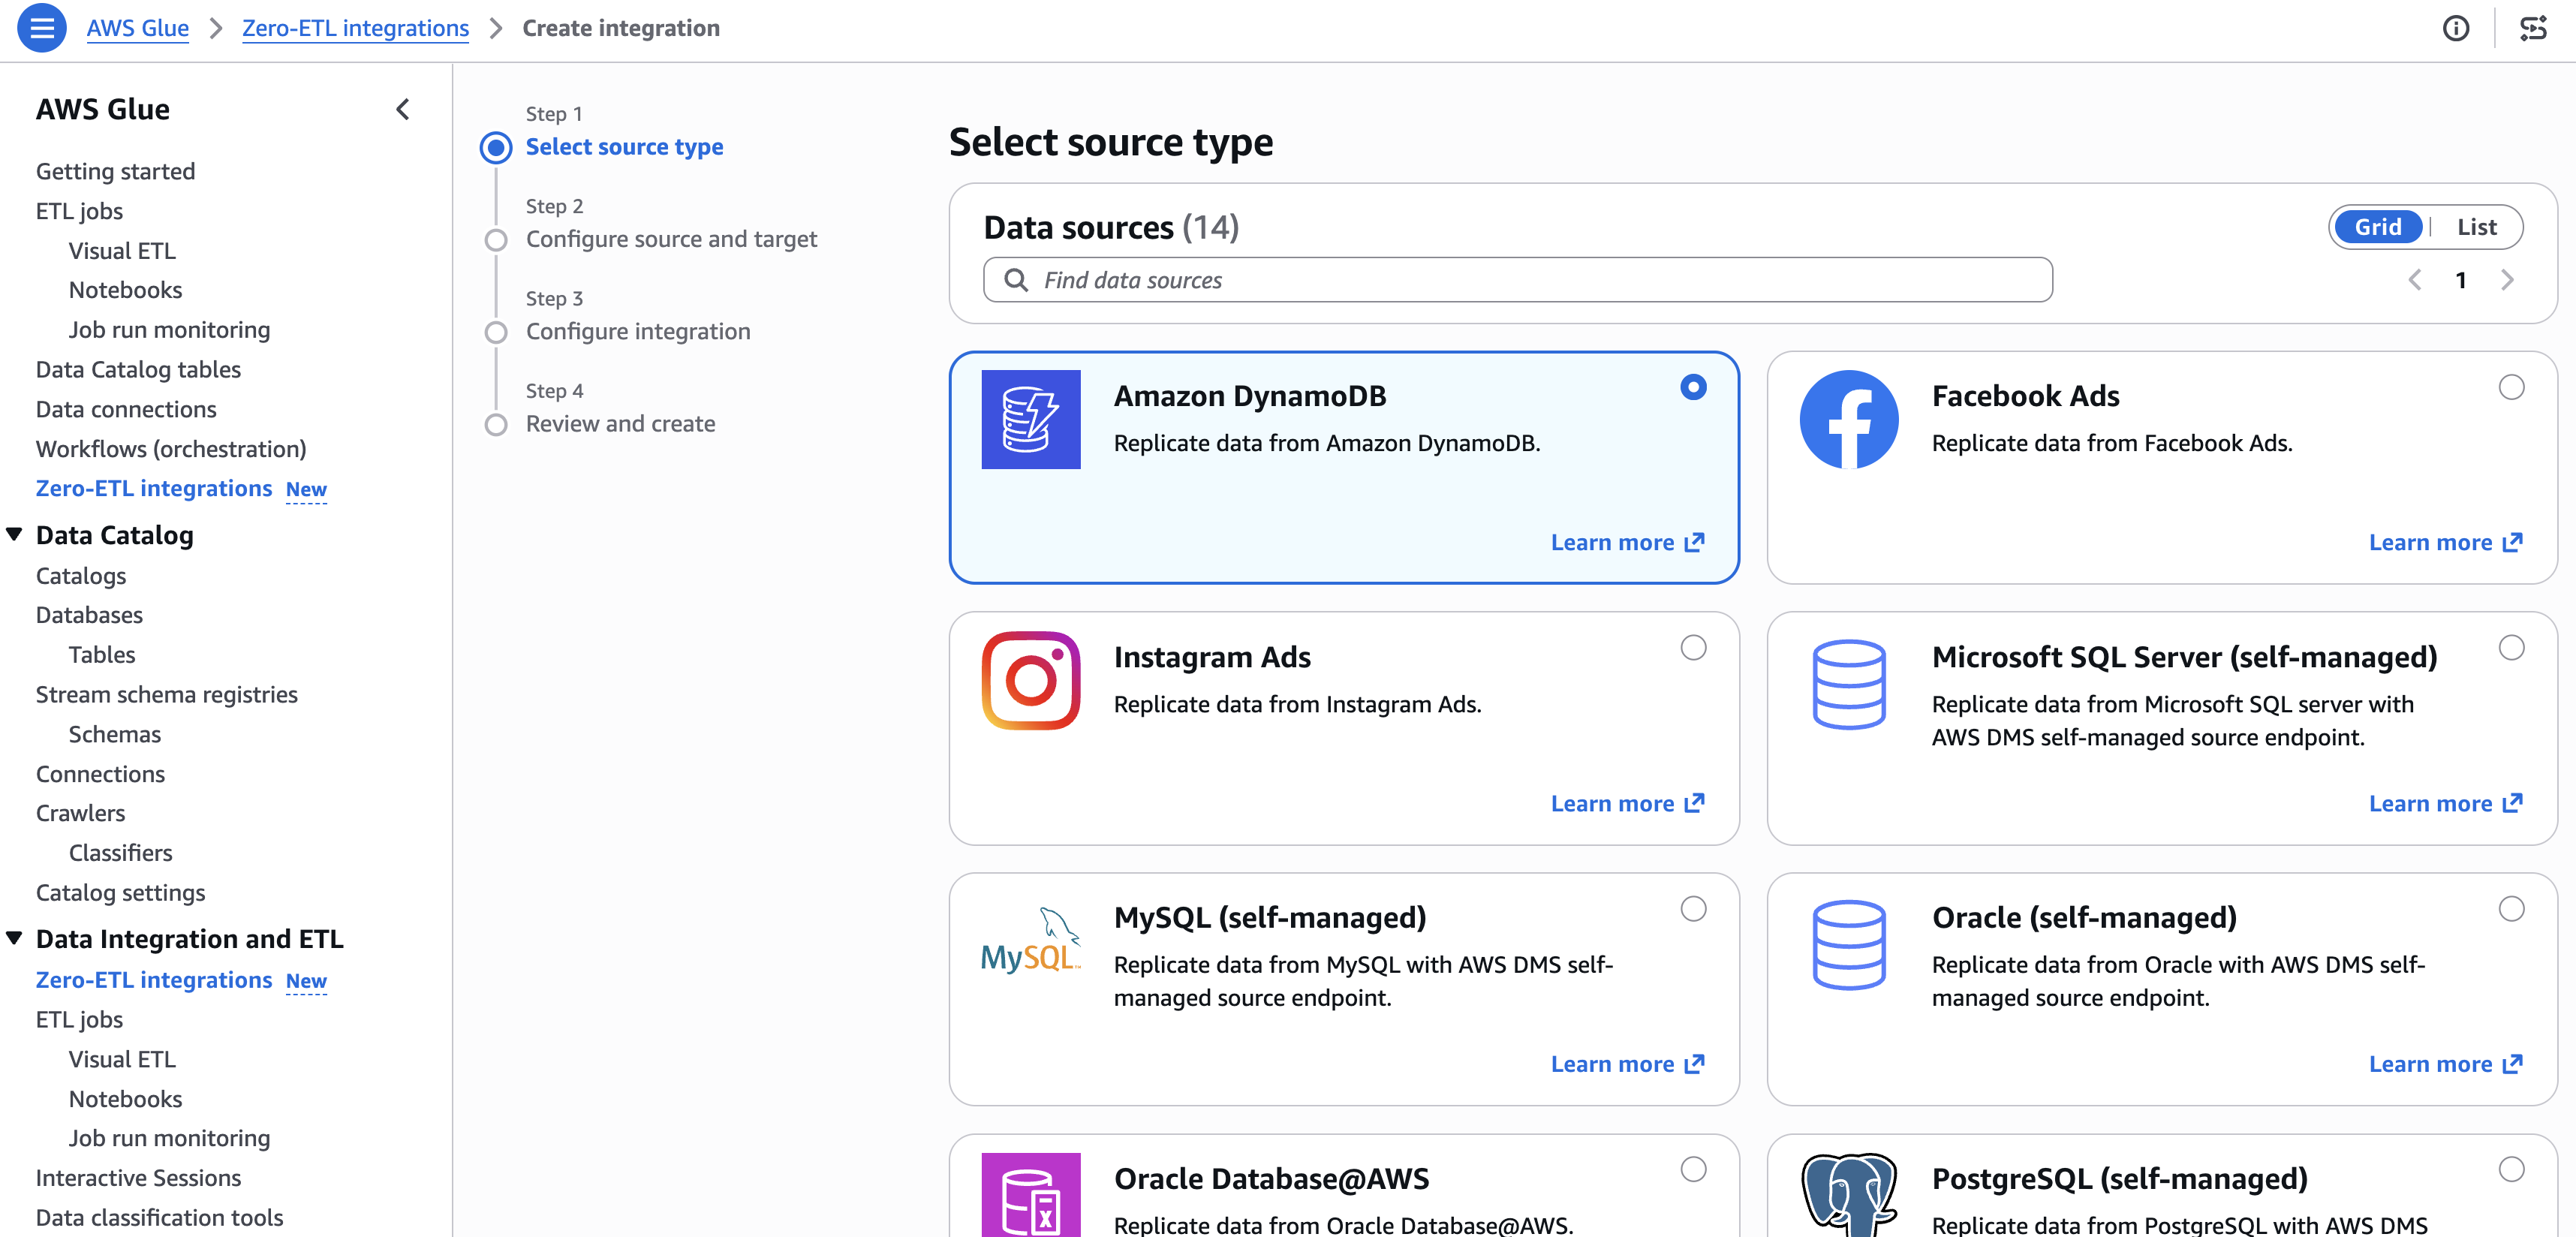
  4. Select Amazon DynamoDB as the source type, then choose Next.

AWS Glue console showing Step 1 of creating a Zero-ETL integration — selecting a source type from 14 available data sources including Amazon DynamoDB, Facebook Ads, Instagram Ads, MySQL, Oracle, PostgreSQL, and Microsoft SQL Server

[Figure 1: Selecting Amazon DynamoDB as the zero-ETL source type]

Step 2: Configure source and target

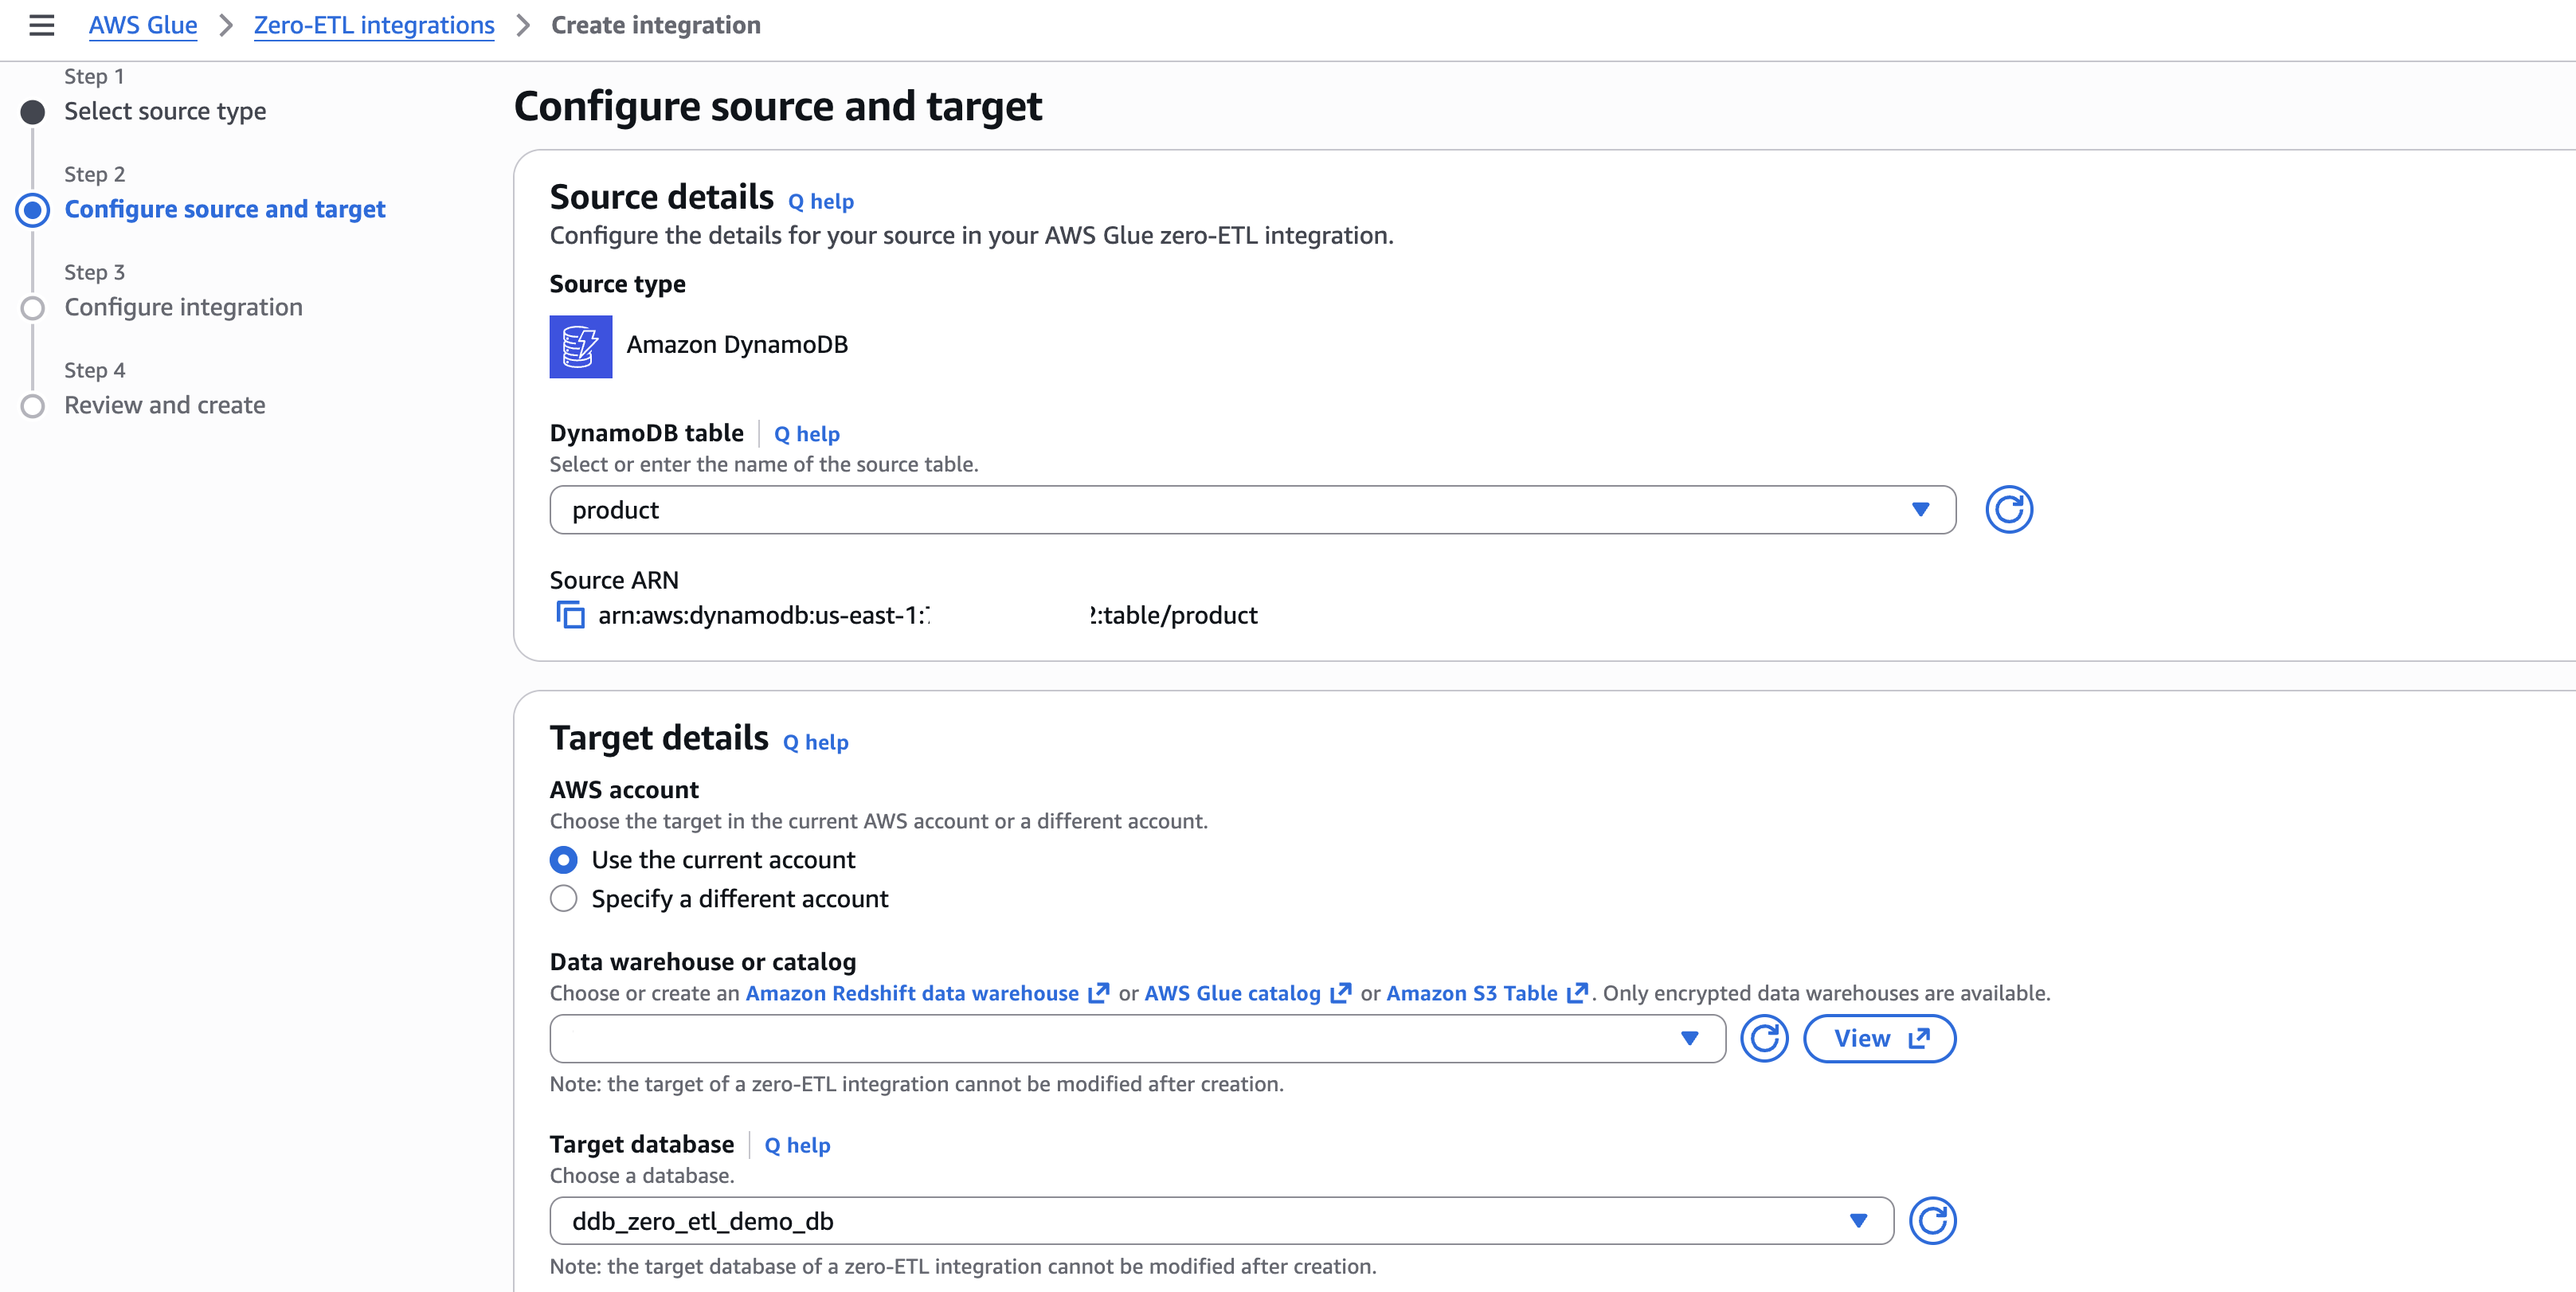
  1. In Source details, select your DynamoDB table (for example, product).
  2. In Target details:
    • Select the current account as target.
    • Choose the catalog and target database (for example, ddb_zero_etl_demo_db).
    • Select the IAM role (for example, zetl-role).

AWS Glue console Step 2 — configuring source and target for a zero-ETL integration with Amazon DynamoDB "product" table as source and an AWS Glue catalog database "ddb_zero_etl_demo_db" as target

[Figure 2: Configuring source DynamoDB table and target database]

Step 3: Configure output settings

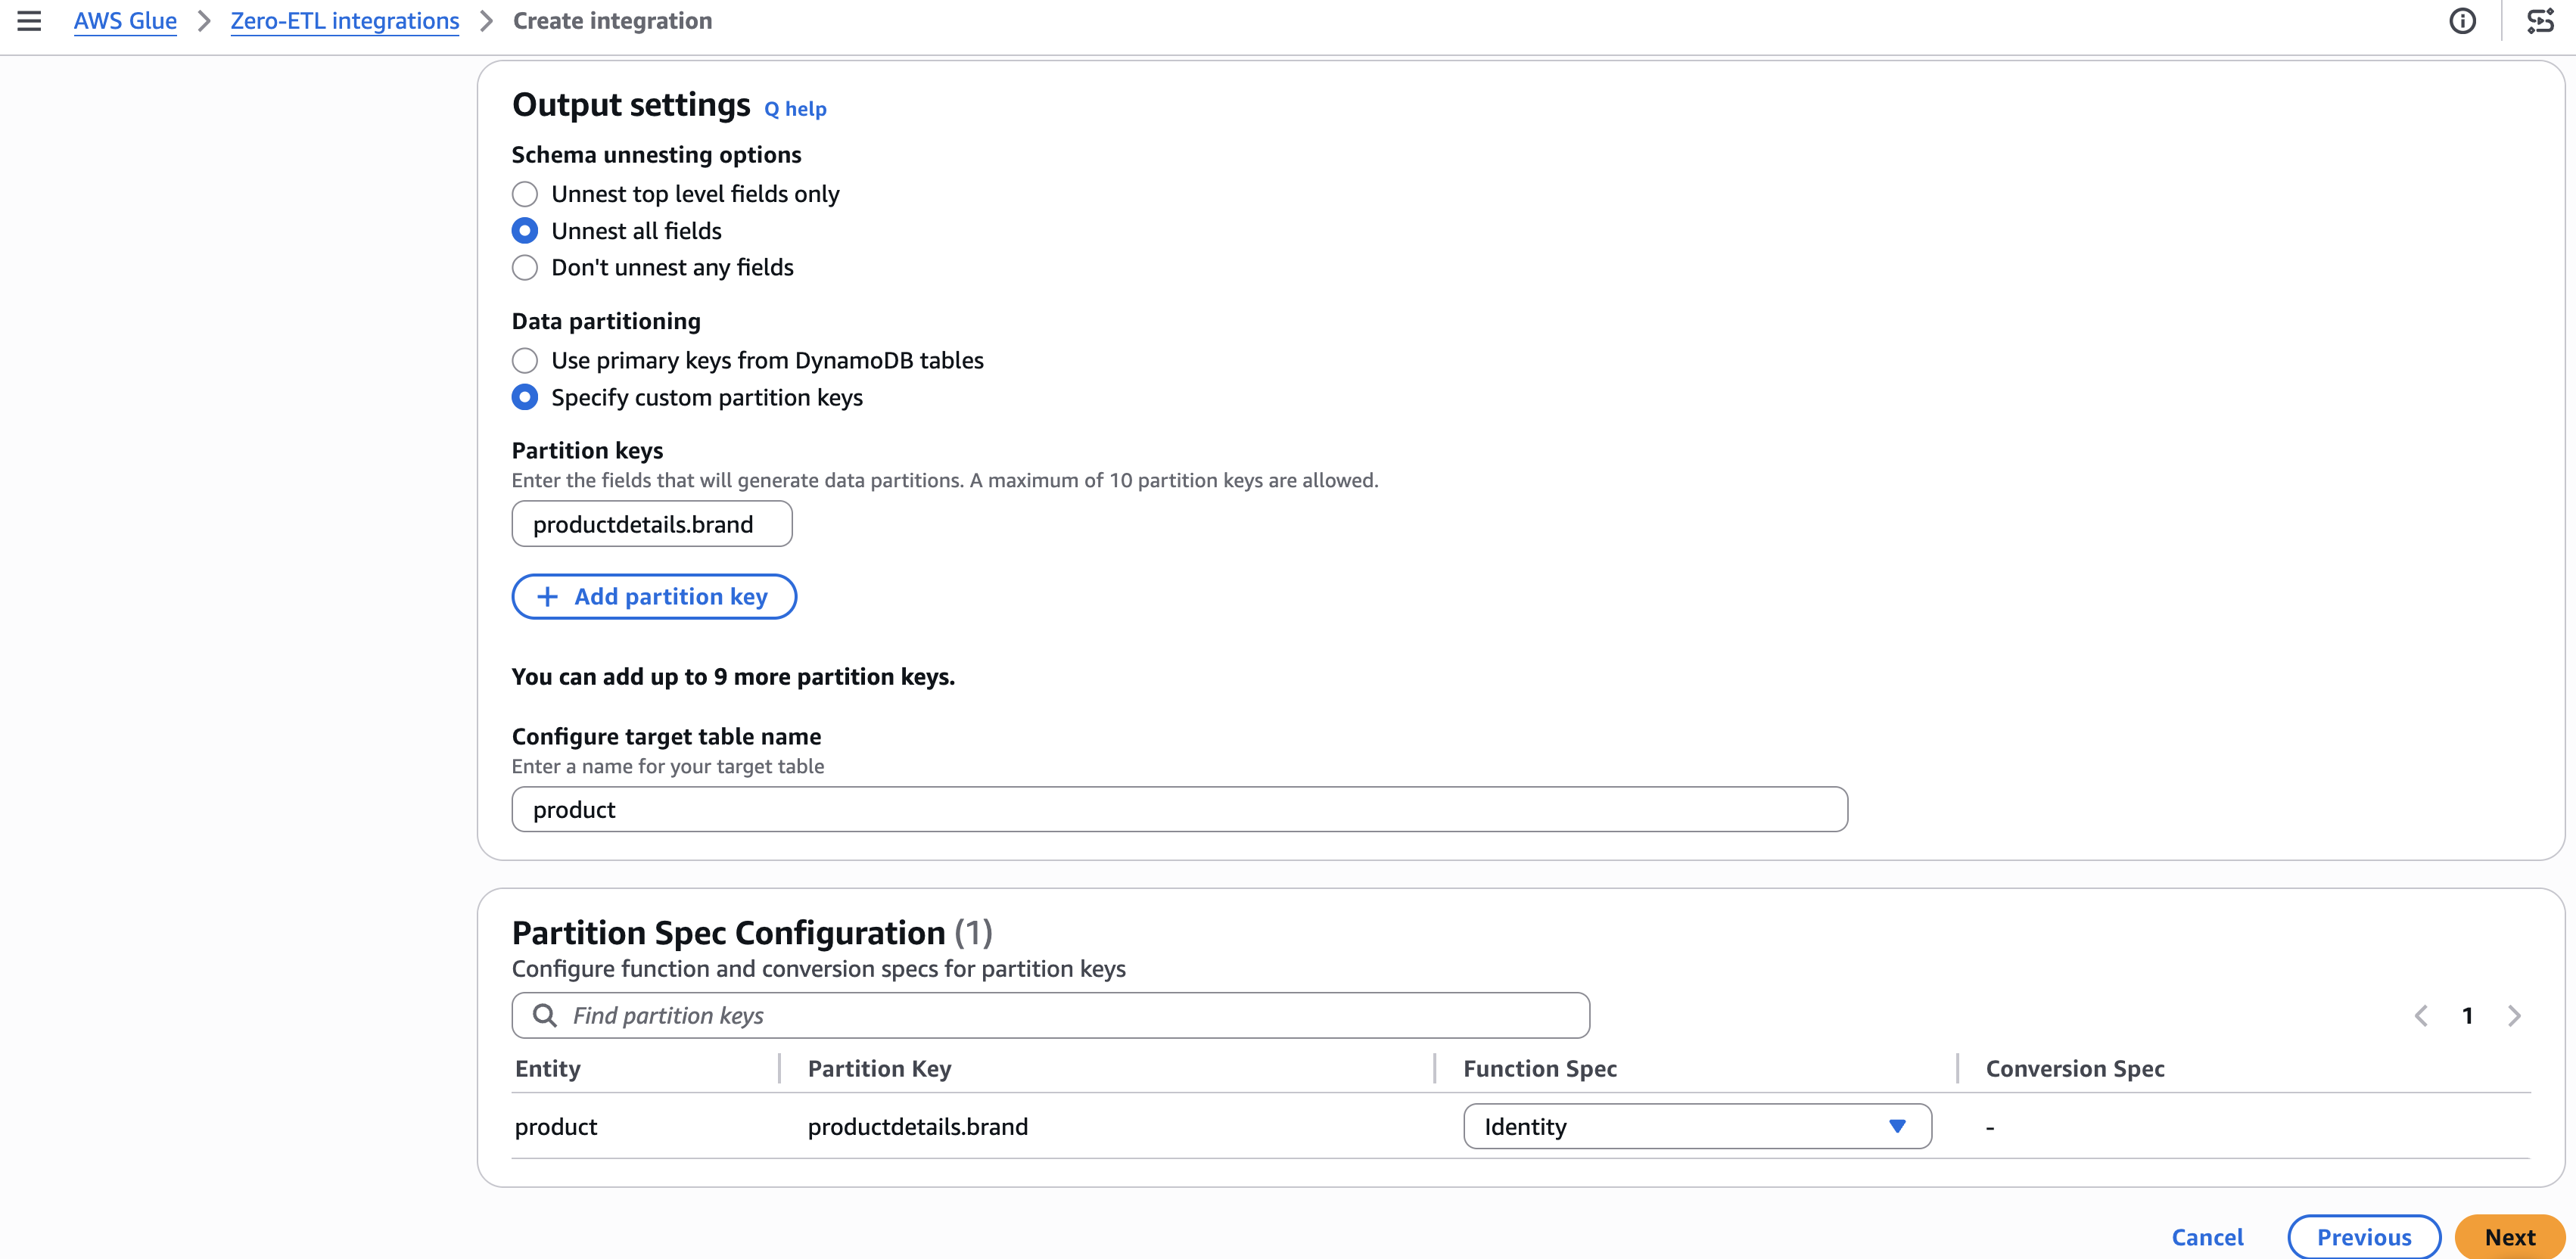
  1. Under Schema unnesting, select Unnest all fields.
  2. Under Data partitioning, select Specify custom partition keys.
  3. Enter the partition key (for example, productdetails.brand) and set the function to Identity.
  4. Choose Next.

AWS Glue Zero-ETL integration output settings showing schema unnesting set to "Unnest all fields," custom partition key "productdetails.brand" configured with Identity function, and target table named "product.

[Figure 3: Configuring schema unnesting and partition key settings]

Step 4: Set integration details

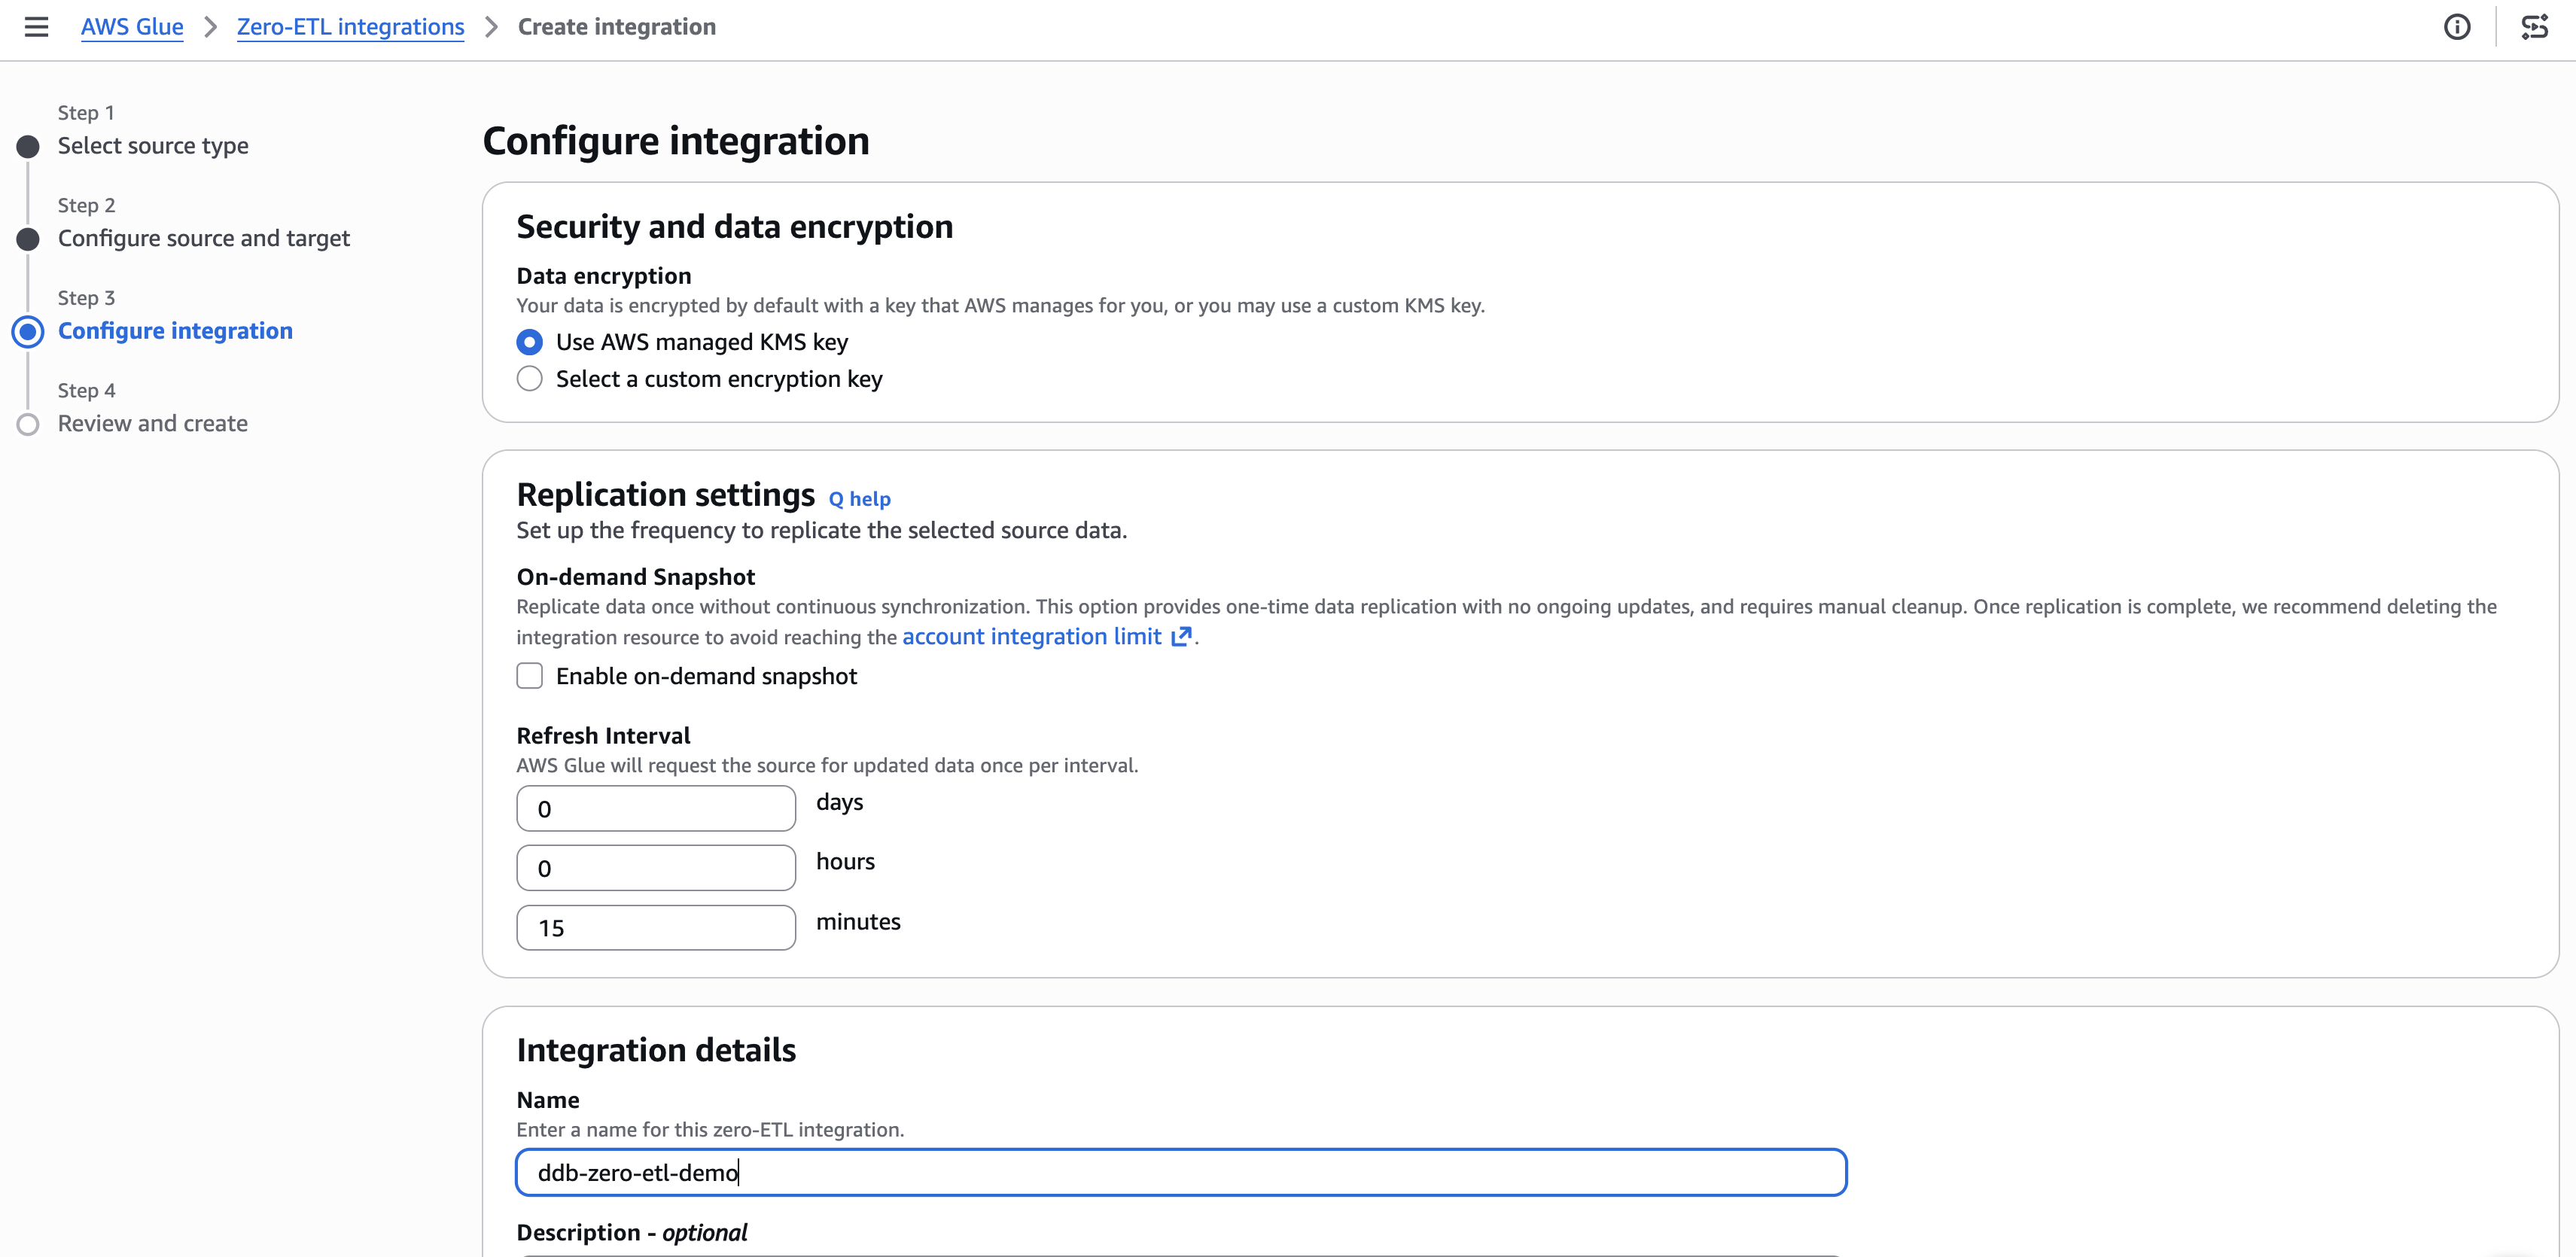
  1. Optionally configure encryption and replication settings. The default refresh interval is 15 minutes.
  2. Enter a name for the integration (for example, ddb-zero-etl-demo).
  3. Choose Next.

AWS Glue Zero-ETL integration Step 3 — configuring security with AWS managed KMS key, replication refresh interval set to 15 minutes, and integration named "ddb-zero-etl-demd

[Figure 4: Configuring encryption and replication settings]

Step 5: Review and create

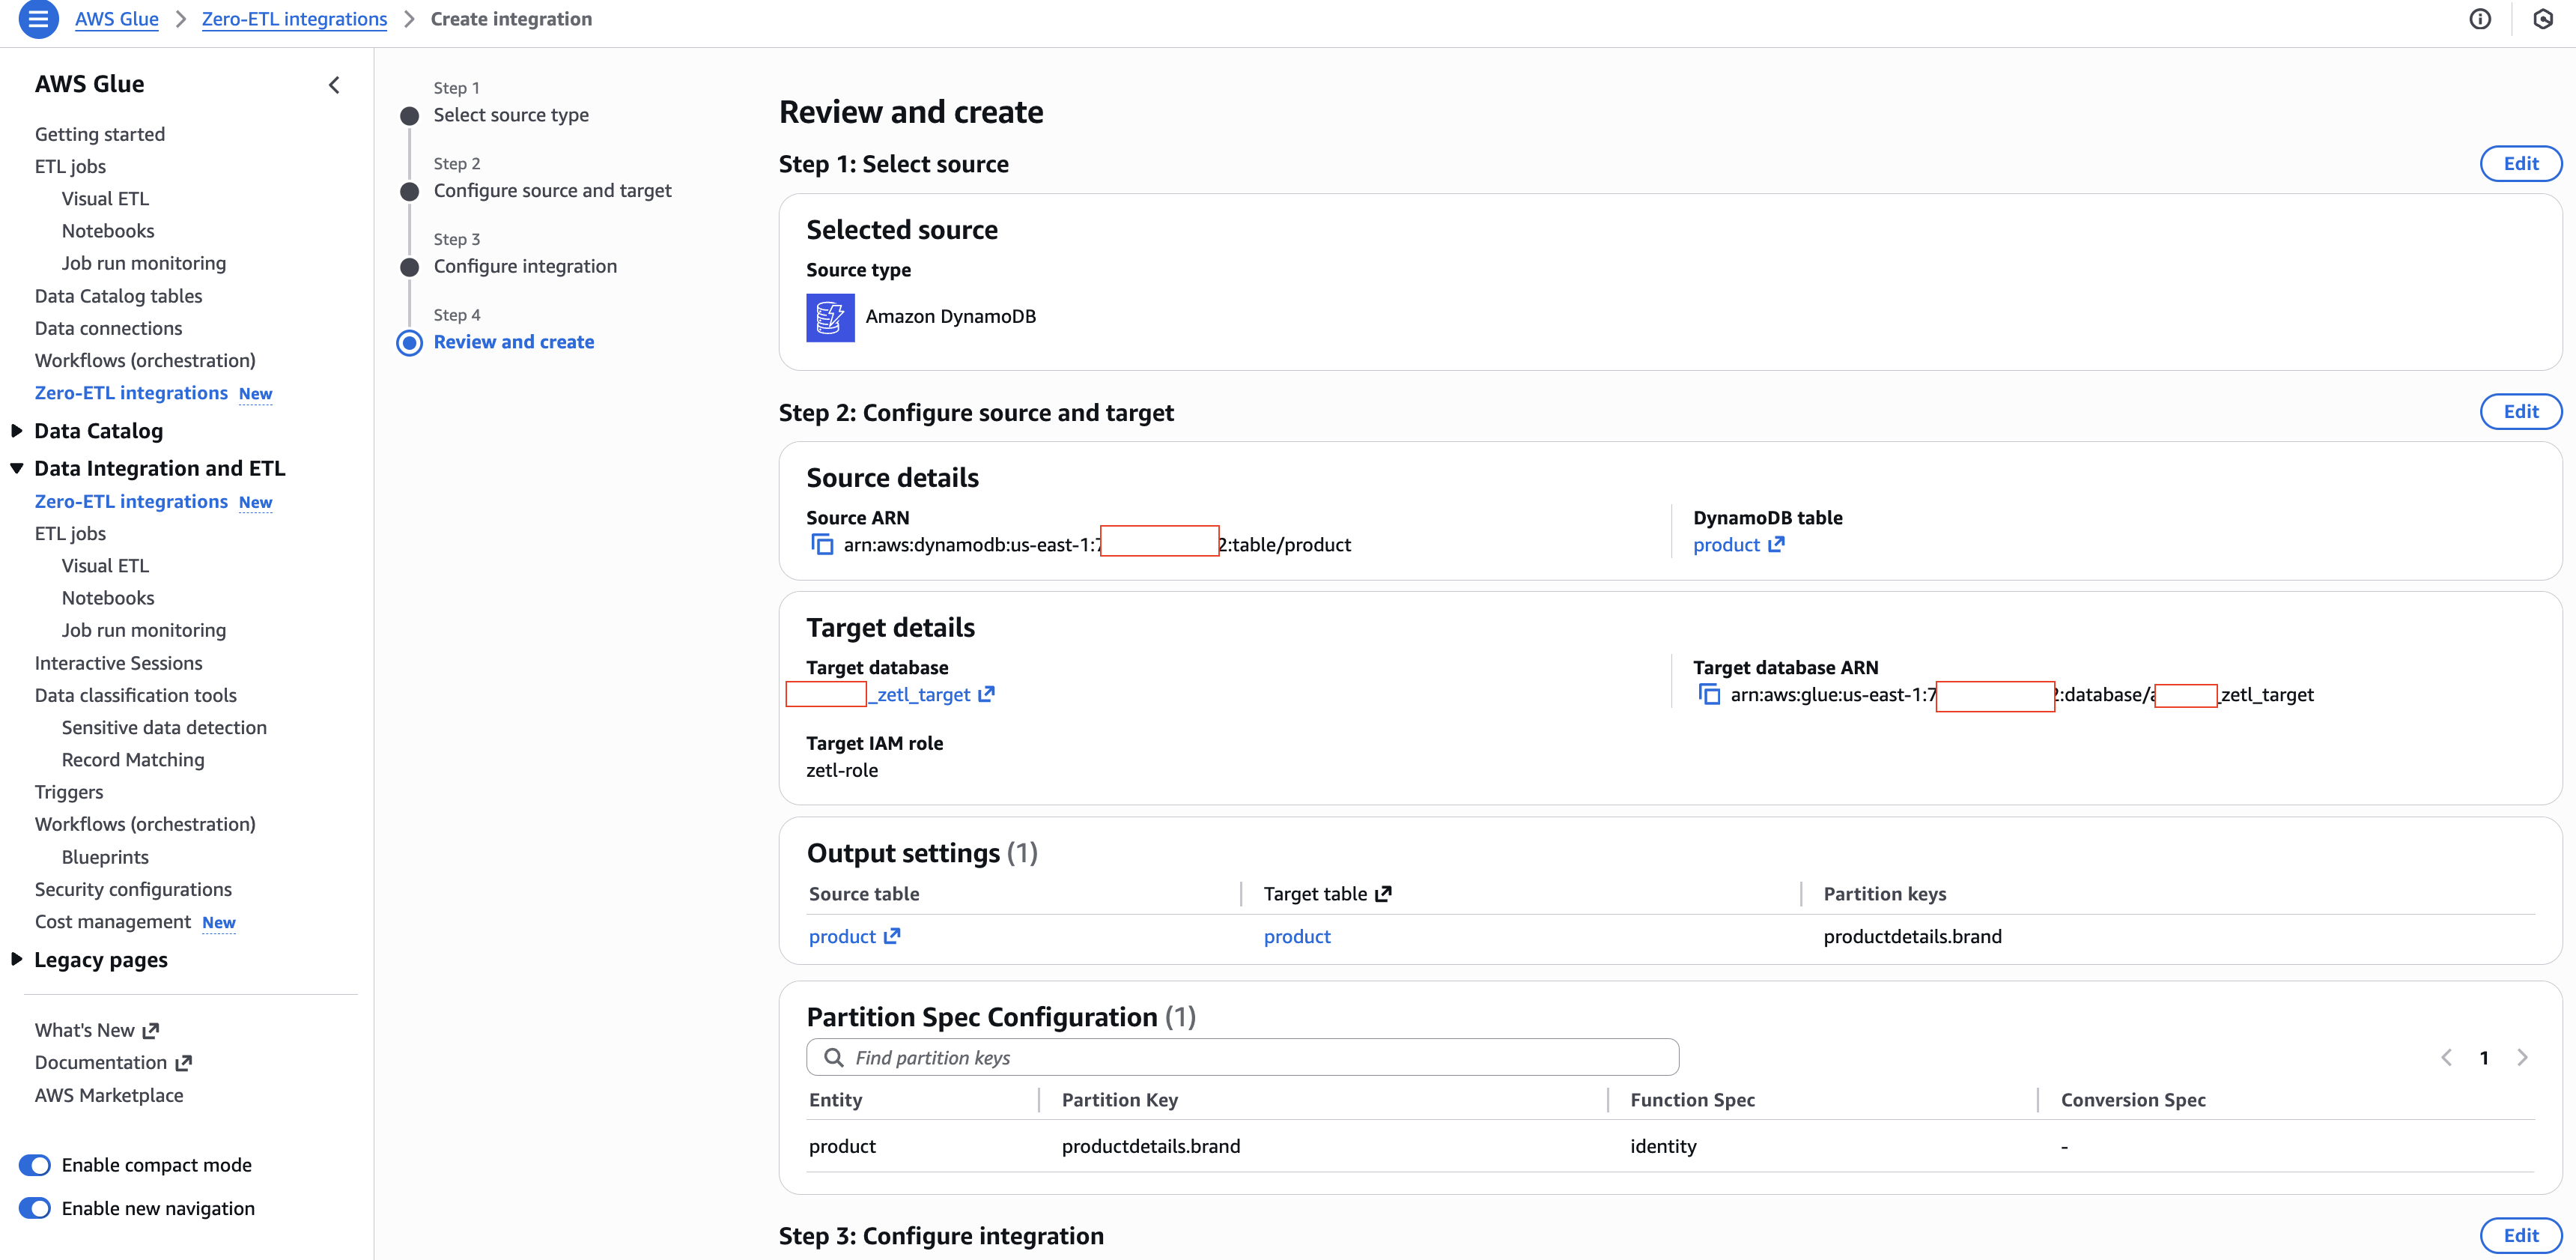
  1. Review your settings and choose Create and launch integration.
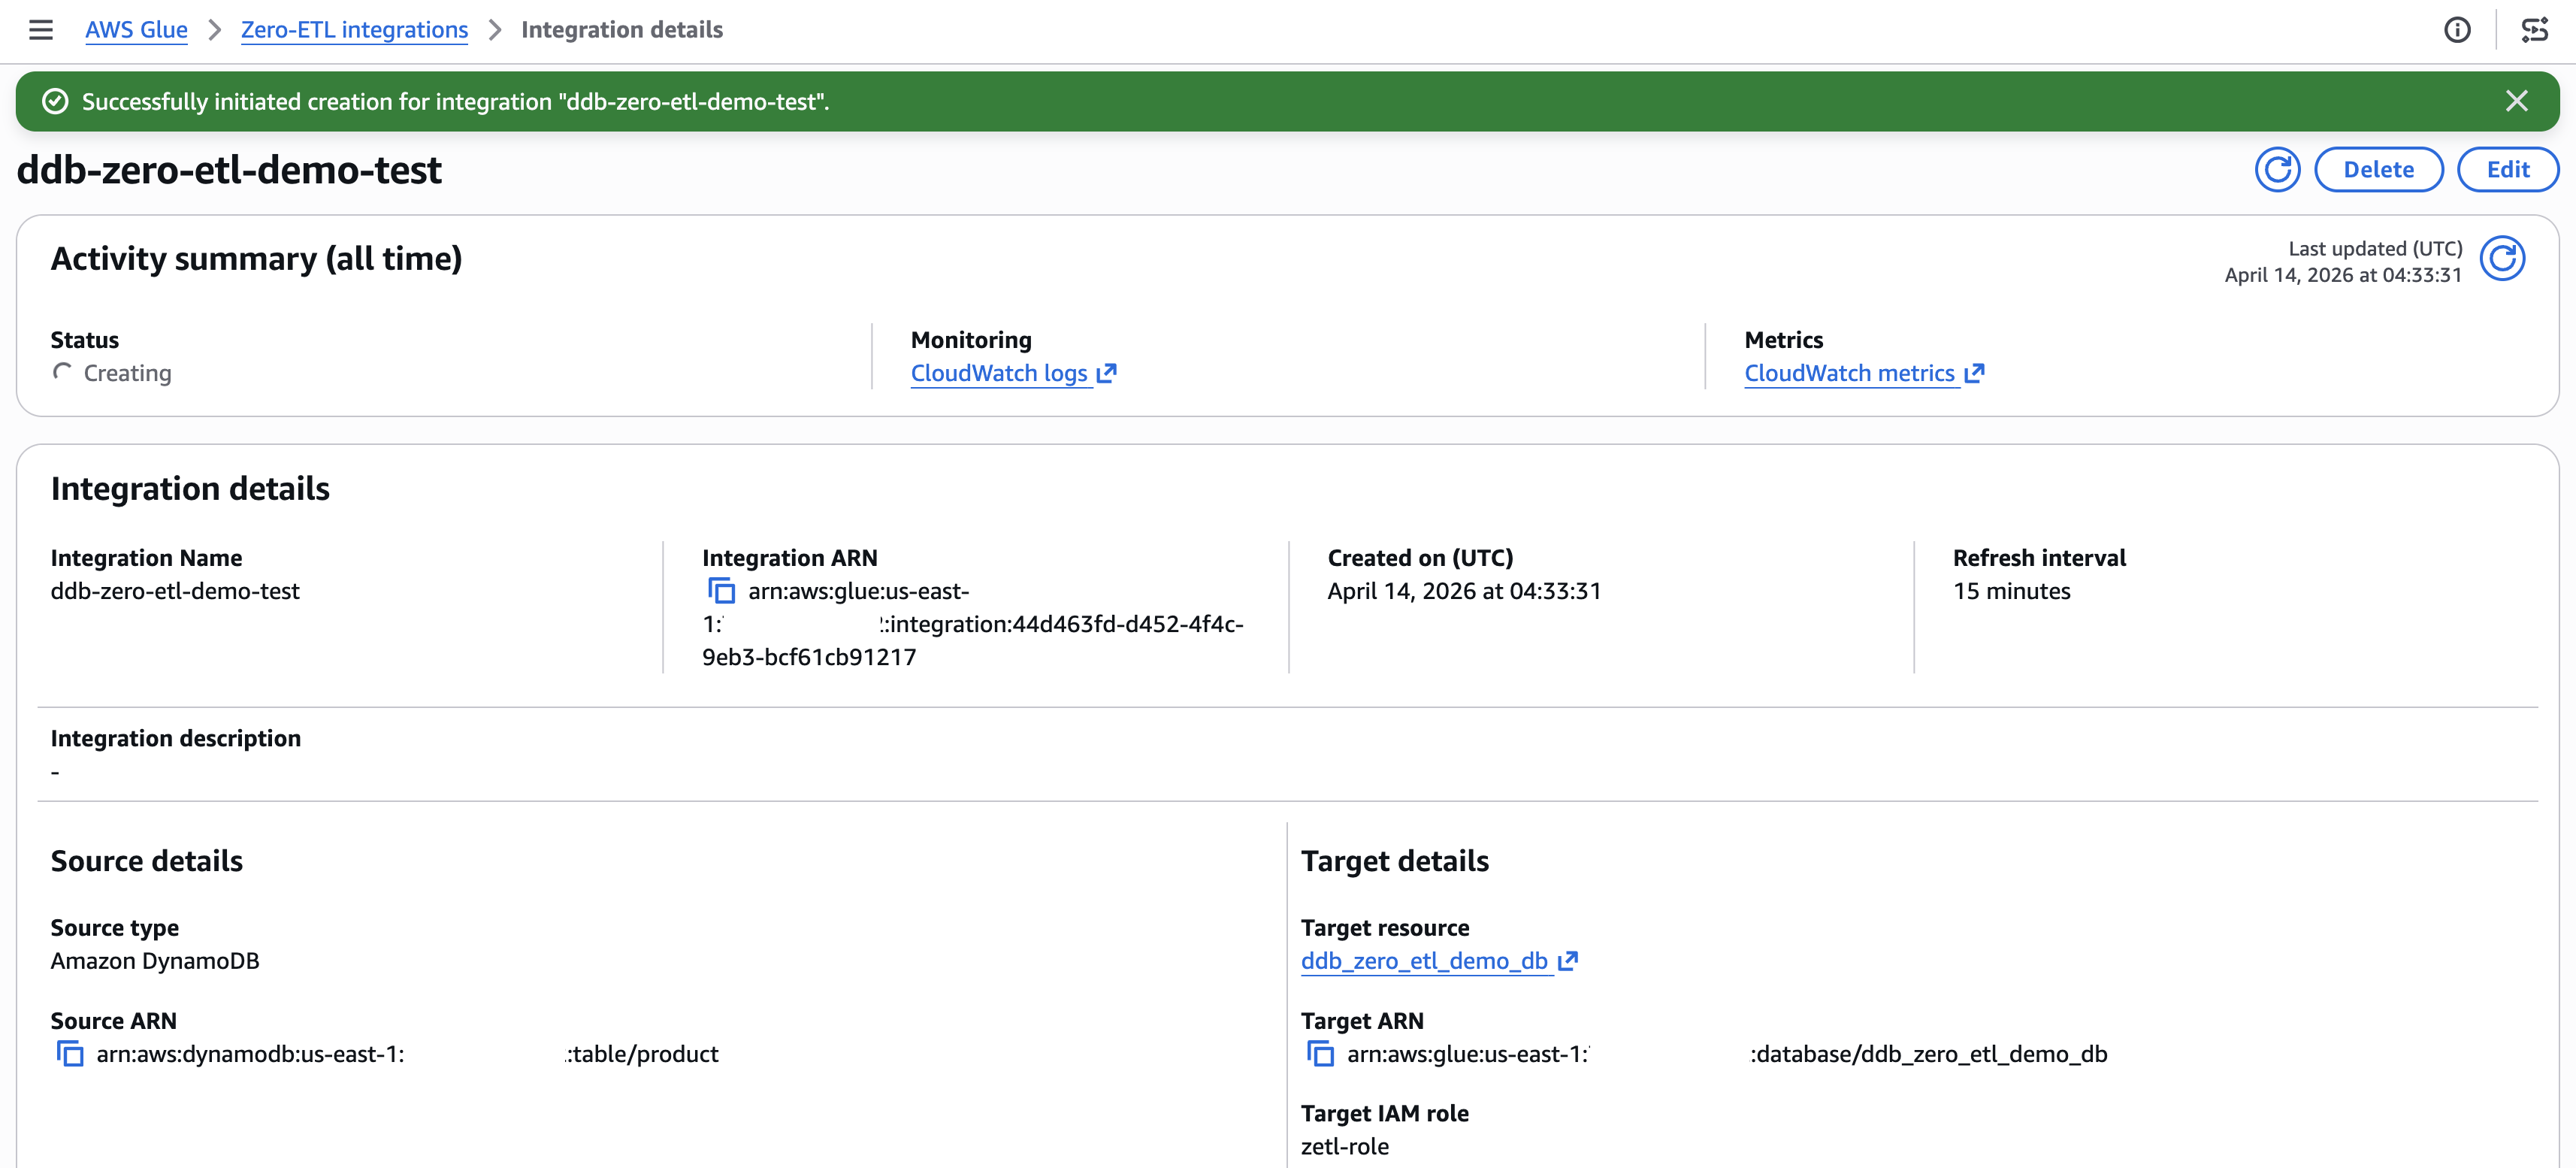
  2. The integration shows as Active within about a minute.

AWS Glue Zero-ETL integration Step 4: Review and Create — showing DynamoDB "product" table as source, Glue database "zett_target" as target with IAM role "zett-role," and partition key "productdetails.brand" with Identity function

[Figure 5: Review and create summary]

AWS Glue Zero-ETL Integration Details page showing "ddb-zero-etl-demo-test" integration with status "Creating," DynamoDB "product" table as source, Glue database "ddb_zero_etl_demo_db" as target, and a 15-minute refresh interval

[Figure 6: Integration active with successful status]

Query the replicated data

After the integration is active and the initial replication completes (typically 15–30 minutes), you can query the data in Amazon Athena.

Preview the replicated data

  1. Open the Amazon Athena console.
  2. In the query editor, select your target database (for example, ddb_zero_etl_demo_db).
  3. Run a preview query:
SELECT * FROM "ddb_zero_etl_demo_db"."product"LIMIT 10;

Verify schema unnesting

With Unnest all fields selected, nested attributes appear as individual columns with dot notation:

SELECT "productdetails.brand", "productdetails.category", "pricing.list_price" 
FROM "ddb_zero_etl_demo_db"."product"
WHERE "productdetails.category" = 'Electronics';

Verify partition pruning

Queries that filter on the partition column (productdetails.brand) automatically skip irrelevant partitions:

SELECT product_id, name, "pricing.list_price"
FROM "ddb_zero_etl_demo_db"."product"
WHERE "productdetails.brand" = 'AudioTech';

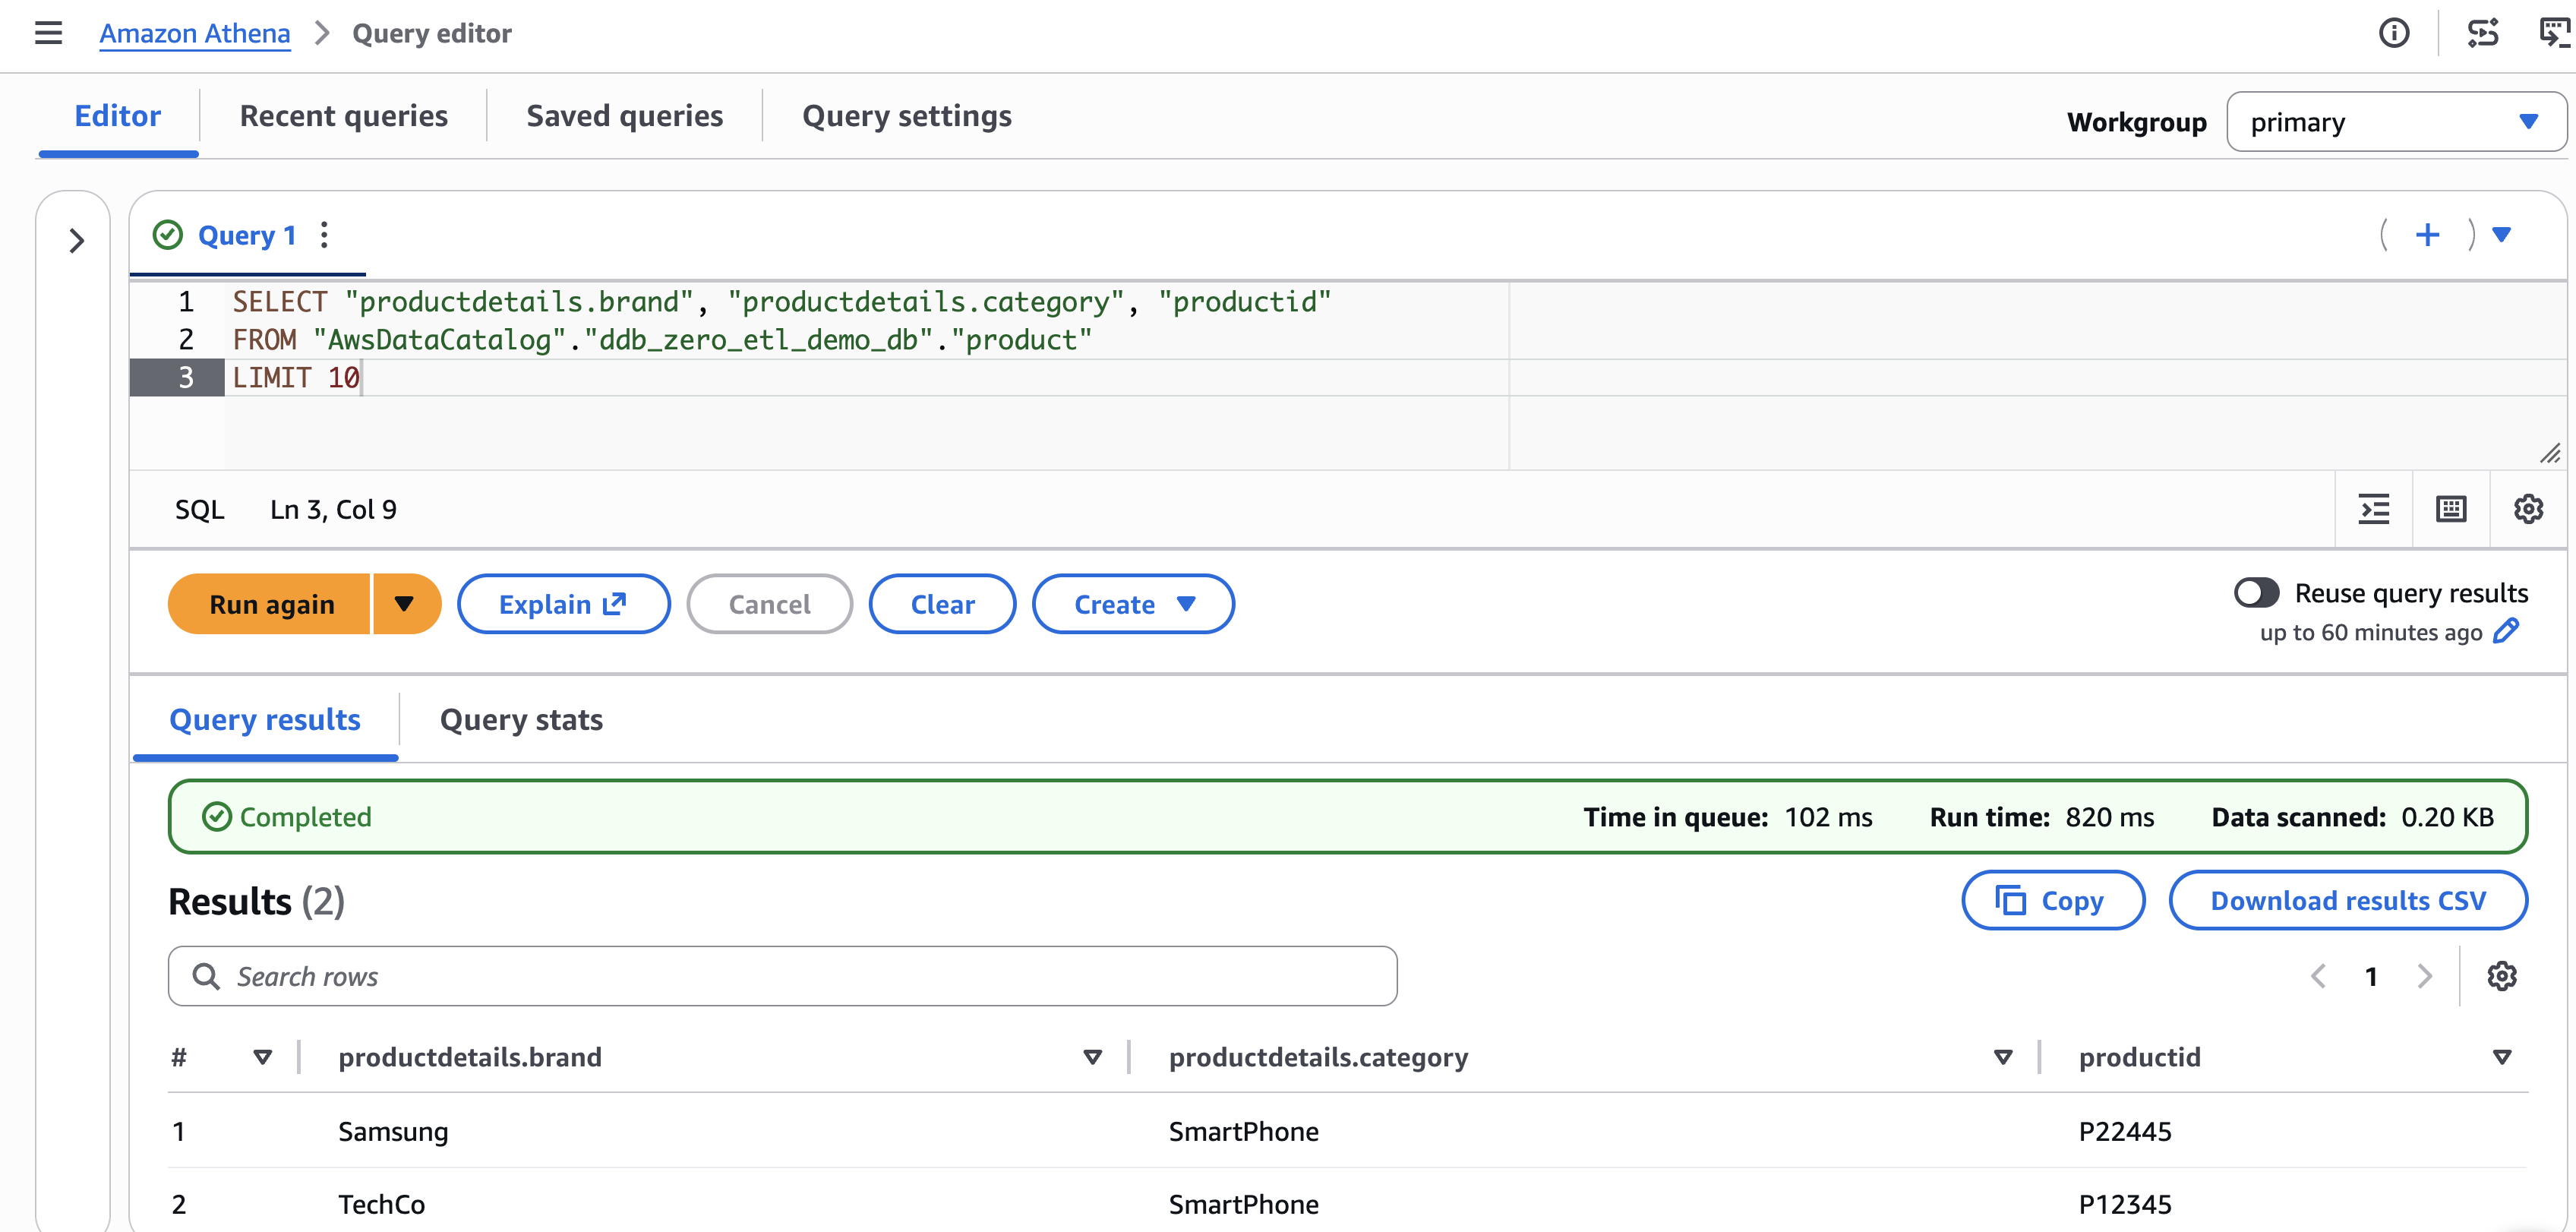
Amazon Athena Query Editor showing a completed SQL query selecting brand, category, and product ID from a DynamoDB zero-ETL Glue catalog table, returning two results: Samsung SmartPhone P22445 and TechCo SmartPhone P12345

[Figure 7: Athena query to retrieve the data from Apache Iceberg lakehouse]

You can verify the partition structure by navigating to the Amazon S3 bucket associated with your database. The data organizes into directories like:

Amazon S3 bucket browser showing the "data/" folder in "ddb-zero-etl-demo-bucket" with two partitioned folders: "productdetails.brand=Samsung/" and "productdetails.brand=TechCo/" — confirming Iceberg partition structure from DynamoDB zero-ETL integration

[Figure 8: Amazon S3 bucket organization for the identity partition productdetails.brand]

Clean up

To avoid ongoing charges, delete the resources in this order:

  1. Delete the zero-ETL integration. In the AWS Glue console, navigate to Zero-ETL integrations, select your integration, and choose Delete. Existing replicated data remains in the target, but new changes stop replicating.
  2. Delete the replicated table. In the AWS Glue Data Catalog, navigate to Tables, select the replicated table, and delete it.
  3. Delete the AWS Glue database. In the Data Catalog, select the database and delete it.
  4. Delete the Amazon S3 data. Empty and delete the S3 bucket associated with the database.
  5. Delete the DynamoDB table. If you created it for this walkthrough, delete the source table.
  6. Delete IAM resources. Remove the IAM role and policies created for the integration.

Conclusion

You configured schema unnesting and data partitioning for a DynamoDB zero-ETL integration, replicated a product catalog table to Apache Iceberg tables in Amazon S3, and verified the results in Amazon Athena. Unnesting flattened nested attributes into directly queryable columns. Partitioning helped the query engine skip irrelevant data, reducing both query time and cost. To take your integration further, try monitoring replication lag and data freshness with Amazon CloudWatch metrics. You can also experiment with different partitioning strategies on a staging table before applying them to production workloads, testing time-based partitioning alongside identity partitioning to find the optimal scheme for your query patterns. For broader analytics coverage, query the same Iceberg tables from Amazon Redshift Spectrum or Amazon EMR alongside Athena. For more details, explore these resources:


About the authors

Raju Ansari

Raju is a Senior Software Development Engineer at AWS, specializing in building scalable, secure, serverless solutions that simplify data analytics and AI agent development. He helps organizations modernize their data analytics infrastructure and develop cutting-edge AI agentic applications. Currently, Raju focuses on building foundational AI services, including Amazon Bedrock Agents, which enable developers to create intelligent, autonomous applications at scale. Outside of work, Raju is passionate about giving back to the tech community. He actively volunteers at IEEE events and mentor early and mid-career professionals

Shashank Sharma

Shashank is an Engineering Leader with over 15 years of experience delivering data integration and replication solutions for first-party and third-party databases and SaaS for enterprise customers. He leads engineering for AWS Glue Zero-ETL and Amazon AppFlow, building fully managed pipelines that replicate data from sources like Salesforce, SAP, DynamoDB, and Oracle into Amazon Redshift and Apache Iceberg-based data lakes. Shashank advises startups on technology strategy and mentors engineers and technical leaders at various career stages

A guide to Airflow worker pool optimization in Amazon MWAA

Post Syndicated from Boyko Radulov original https://aws.amazon.com/blogs/big-data/a-guide-to-airflow-worker-pool-optimization-in-amazon-mwaa/

Optimizing the Airflow worker pool configuration in Amazon Managed Workflows for Apache Airflow (Amazon MWAA), the AWS fully managed Apache Airflow service, is an important yet often overlooked strategy for scaling workflow operations. Tasks queued for longer periods can create the illusion that additional workers are the solution, when in reality the root cause might lie elsewhere. The decision to scale isn’t always straightforward. DevOps engineers and system administrators frequently face the challenge of determining whether adding more workers will solve their performance issues or only increase operational cost without addressing the root cause.

This post explores different patterns for worker scaling decisions in Amazon MWAA, focusing on the task pool mechanism and its relationship to worker allocation. By examining specific scenarios and providing a practical decision framework, this post helps you determine whether adding workers is the right solution for your performance challenges, and if so, how to implement this scaling effectively.

Main patterns

This section discusses the most frequently seen problems that raise the question if adding additional workers would improve the health of your environment.

High CPU

Airflow serves as a workflow management platform that coordinates and schedules tasks to be run on external processing services. It acts as a central orchestrator that can trigger and monitor tasks across various data processing systems like AWS Glue, AWS Batch, Amazon EMR, and other specialized data processing tools. Rather than processing data itself, Airflow’s strength lies in managing complex workflows and coordinating jobs between different systems and services.

In Analytics and Big Data environments, there is a prevalent misconception that saturated resources automatically warrant adding more capacity. However, for Amazon MWAA, understanding your workflow characteristics and optimization opportunities should precede scaling decisions.

As you scale up your workflows, resource utilization of the Airflow clusters naturally increases. When workers consistently operate at full capacity, it may seem intuitive to add additional compute resources. However, this approach often masks underlying inefficiencies rather than resolving them.

For example, in Amazon MWAA if you are running a single task that is consuming 100% of the available CPU on your Amazon MWAA worker, adding additional workers will not resolve the problem as the task is not optimized nor split into smaller parts. As such, increasing the number of minimum workers will not bring the expected effect but will only increase the operating costs.

When your Amazon MWAA workers are consistently running above 90% CPU or Memory utilization, you’ve reached a critical decision point. Before taking actions, it is essential to understand the root cause. You have three primary options:

  1. Scale horizontally by adding additional workers to distribute the load.
  2. Scale vertically by upgrading to a larger environment class for more resources per worker.
  3. Optimize your DAGs and scheduling patterns to be more efficient and consume fewer resources.

Each approach addresses different underlying issues, and choosing the right path depends on identifying whether you are facing a capacity constraint, resource-intensive task design, or workflow inefficiency. For guidance on optimization strategies, please refer to Performance tuning for Apache Airflow on Amazon MWAA.

To monitor the CPUUtilization and MemoryUtilization on the workers, refer to the Accessing metrics in the Amazon CloudWatch console and choose the corresponding metrics.

  1. Select a time window long enough to show usage patterns.
  2. Set period to 1 Minute.
  3. Set statistics to Maximum.

Long queue time

Sometimes Airflow tasks are stuck in a queued state for a long time, which prevents DAGs from completing on time.

In Amazon MWAA, each environment class comes with configured minimum and maximum worker nodes. Each worker provides a pre-configured concurrency, which is the number of tasks that can run simultaneously on each worker at any given time. The behavior is controlled through celery.worker_autoscale=(max,min).

For example, if you have minimum 4 mw1.small workers, with default Airflow configuration, you will be able to run 20 concurrent tasks (4 workers x 5 max_tasks_per_worker). If your system suddenly requires more than 20 tasks to execute concurrently, this will result in an autoscaling event. Amazon MWAA will decide how to scale your workers efficiently, and trigger the process. The autoscaling process, however, requires additional time to provision new workers resulting in additional tasks in queued status. To mitigate this queuing issue, consider the following:

  1. If the CPU utilization on the workers is low, increasing the max value in celery.worker_autoscale=(max,min) can reduce the time tasks stay in queued state as each worker will be able to process more tasks concurrently. Airflow worker can take tasks up to the defined task concurrency regardless of the availability of its own system resources. As a result, the base worker may reach 100% CPU/Memory utilization before Autoscaling takes effect.
  2. If you do not want to increase the task concurrency on the workers, increasing the minimum worker count can also be beneficial because having more available workers allows a higher number of tasks to run concurrently.

Scheduling delays

Adding new DAGs can not only affect your system resources, but it can also create uneven scheduling patterns. Some DAGs may experience delayed execution because of resource competition, even when the overall environment metrics appear healthy. This scheduling skew often manifests as inconsistent task pickup times, where certain workflows consistently wait longer in the queue while others execute promptly.

When Amazon CloudWatch metrics show increasing variance in task scheduling times, particularly during periods of high DAG activity, it signals the need for environment optimization. This scenario requires careful analysis of execution patterns and resource utilization to determine if:

  1. While adding workers can help distribute the workload, this solution is most effective when the high utilization is primarily because of task execution load rather than DAG parsing or scheduling overhead. Adding more minimum workers will allow you to execute more tasks in parallel. For example, if you observe the value of AWS/MWAA/ApproximateAgeOfOldestTask to be steadily increasing, it means that the workers are not able to consume the messages from the queue fast enough. Additionally, you can also monitor the AWS/MWAA/QueuedTasks to identify similar patterns.
  2. Upgrading the environment class would provide better scheduling capacity. If the Scheduler is showing signs of strain or if you’re seeing high resource utilization across all components, upgrading to a larger environment class might be the most appropriate solution. This provides more resources to both the Scheduler and Workers, allowing for better handling of increased DAG complexity and volume. To validate the same, use AWS/MWAA/CPUUtilization and AWS/MWAA/MemoryUtilization in the Cluster metrics and choose Scheduler, BaseWorker and AdditionalWorker metrics.
  3. Restructuring DAG schedules would reduce resource contention.

The key is to understand your workflow patterns and identify whether the scheduling delays are because of insufficient worker capacity or other environmental constraints.

Anti patterns

This section showcases the most common anti patterns which make MWAA users think that adding more workers will improve performance.

Underutilized workers

When evaluating Amazon MWAA performance bottlenecks, it’s important to distinguish resource constraints and DAG design inefficiencies before scaling the environment.

Sometimes the Amazon MWAA environment has the capacity to run 100 tasks concurrently but your queue metrics (AWS/MWAA/RunningTasks) show only 20 tasks active most of the time with no tasks remaining in queued state. In such scenarios, you are advised to check Amazon CloudWatch for consistently low CPU and memory usage on existing workers during peak workload times. If this is confirmed, it is usually an indication of inefficiencies in DAG design, scheduling patterns, or Airflow configuration.

You have two primary options to address this:

1. Downsize: If you do not expect your workload to increase, it is safe to assume you have over-provisioned your cluster. Start by removing any extra workers first and finally resolve to downsizing your environment class.

2. Optimize: Fine tune your DAG scheduling and airflow configuration through Pools and Airflow configuration for concurrency to increase the throughput of your system.

Misconfigured Airflow configurations that create artificial bottlenecks

In Apache Airflow, performance bottlenecks often occur because of configuration settings, not actual resource constraints. At such times, DAG executions get delayed not because of insufficient compute, but because of incorrect concurrency configuration.

Efficient use of Amazon MWAA requires reviewing not only resource utilization for Workers and Schedulers but also concurrency configurations for artificially created bottlenecks. Sometimes one restrictive configuration prevents the scaling benefits of larger environment or additional workers. Always audit Airflow configurations if performance seems limited even when system metrics suggest spare capacity.

Important consideration: Amazon Managed Workflows for Apache Airflow (Amazon MWAA) does not automatically update the worker concurrency configuration when you change the environment class. This behavior is important to understand when scaling your environment. If you initially create an mw1.small environment, where each worker can handle up to 5 concurrent tasks by default. When you upgrade to a medium environment class (which supports 10 concurrent tasks per worker by default), the concurrency setting remains at 5 for in-place updated environments. You must manually update the concurrency configuration to take full advantage of the increased capacity available in the medium environment class.

Because of this you need to also update the Airflow configurations that control concurrency whenever you update the environment class. To update the concurrency setting after upgrading your environment class, modify the celery.worker_autoscale configuration in your Apache Airflow configuration options. This makes sure your workers can process the maximum number of concurrent tasks supported by your new environment class.

Other times, an Amazon MWAA environment can be constrained by max_active_runs or DAG concurrency controls instead of actual resource limits. These configuration-based throttles prevent tasks from running, even when the worker instances have available compute to handle the workload.

There is an important distinction between the two. Configuration limits act as artificial caps on parallelism, while true resource limits indicate that workers are fully utilizing their CPU or memory capacity. Understanding which type of constraint affects your environment helps you determine whether to adjust configuration settings or scale your infrastructure.

Adjusting Airflow configurations such as Pools, concurrency, max_active_runs solves performance problems without scaling workers. Some of the configurations you can use to control this behavior:

  1. max_active_runs_per_dag (DAG level): Controls how many DAG runs for a given DAG are allowed at the same time. If set to 2, only 2 DAG runs can run concurrently, even if there is plenty of worker capacity left. Extra runs queue, making the DAG executions slow even though workers are idle.
  2. max_active_tasks:Controls the concurrency field in a DAG definition (or setting at environment level) limits the number of tasks from the DAG running at any moment, regardless of overall system capacity or number of workers.
  3. Pools:Pools restrict how many tasks of a certain type (often resource heavy) can run at once. A pool with only 3 slots will throttle any tasks above 3 assigned to that pool, leaving workers idle.
  4. Execution timeouts and retries: If not tuned, failed tasks might fill up slots unnecessarily, stuck tasks can block worker slots and slow queue processing.
  5. Scheduling intervals and dependencies: Overlapping or inefficient scheduling may cause idle periods or excess contention for resources, affecting real throughput.

How Airflow configurations can override each other

Airflow has multiple layers of concurrency and scheduling controls. Some at the environment level, some at the DAG/task level, and others for pools. Sometimes more restrictive settings override more permissive ones, resulting in unexpected queue buildup.

DAG level vs Environment level: If “max_active_runs_per_dag” (DAG level) is lower than the environment-level “max_active_runs_per_dag” or system wide concurrency, the DAG setting is used, throttling tasks even if the environment could do more.

Task level overrides: Individual task definitions can have their own parameters like “max_active_tis_per_dag” which can cap runs per task and create a bottleneck if set lower than global settings.

Order of precedence: The most restrictive relevant configuration at any level (Environment, DAG, Task) effectively sets the upper bound for parallel task execution.

Setting Location Setting Effect on task throughput
Environment Level parallelism Max total tasks running on Scheduler
DAG Level max_active_runs Max simultaneous DAG runs
Task Level concurrency Max concurrent task for that DAG

Performance issues often resemble resource exhaustion, but actually derive from overly restrictive configurations. Audit all the preceding parameters carefully. You can loosen restrictive values step by step and monitor their effect before deciding to scale your cluster further. This approach ensures optimal and cost-efficient usage of your cloud resources without paying for idle capacity.

Slow resource depletion from memory leaks

A common scenario for memory leak or slow resource depletion in Amazon MWAA is when DAGs and tasks begin to fail or slow down over time. Scaling workers or increasing environment size does not resolve the underlying issue. This happens because the root cause is not a lack of capacity but rather an application-level leak that causes persistent exhaustion.

For example, as Airflow continuously runs tasks and parses DAGs over time, memory consumption can steadily increase across the environment. This might manifest as an Amazon MWAA metadata database experiencing declining FreeableMemory metrics despite consistent or even reduced workloads. When this occurs, database query performance gradually declines as memory resources become constrained for scheduler/worker & metadata database, ultimately affecting overall environment responsiveness since Airflow depends heavily on its metadata database for critical operations. This scenario is similar to how an application might create database connections without properly closing them, leading to resource exhaustion over time.

Graph: Declining FreeableMemory and MemoryUtilization

Common causes:

  1. Connection pool exhaustion: DAGs that fail to properly close database connections can lead to connection pool exhaustion and memory leaks in the database.
  2. Resource-intensive operations: Complex, long-running queries or XCOM operations against the metadata database can consume excessive memory.
  3. Inefficient DAG design: DAGs with numerous top-level Python calls can trigger database queries during DAG parsing. For instance, using variable.get() calls at the DAG level rather than at the task level creates unnecessary database load.

Recommended solutions:

  1. Implement Amazon CloudWatch monitoring: Establish Amazon CloudWatch alarms for FreeableMemory with appropriate thresholds to detect issues early.
  2. Regular database maintenance: Perform scheduled database clean-up operations to purge historical data that is no longer needed.
  3. Optimize DAG code: Refactor DAGs to move database operations like variable.get() from the DAG level to the task level to reduce parsing overhead.
  4. Connection management: Make sure all database connections are properly closed after use to prevent connection pool exhaustion.

By following the preceding recommendations you can maintain healthy memory utilization for the metadata database and maintain optimal performance of your Amazon MWAA environment without needing to scale workers.

Conclusion

The decision to add workers in Amazon MWAA environments requires careful consideration of multiple factors beyond simple task queue metrics. In this post, we showed that while adding workers can address certain performance challenges, it’s often not the optimal first response to system bottlenecks.

Key considerations before scaling workers include:

  1. Root cause analysis
    • Verify whether high CPU/memory usage stems from task optimization issues.
    • Examine if queuing problems result from configuration constraints rather than resource limitations.
    • Investigate potential memory leaks or resource depletion patterns.
  2. Configuration optimization
    • Review and adjust Airflow parameters (concurrency settings, pools, timeouts).
    • Understand the interaction between different configuration layers.
    • Optimize DAG design and scheduling patterns.

The most successful Amazon MWAA implementations follow a systematic approach: first optimizing existing resources and configurations, then scaling workers only when justified by data-driven capacity planning. This approach ensures cost-effective operations while maintaining reliable workflow performance.

Remember that worker scaling is only one tool in the Amazon MWAA optimization toolkit. Long-term success depends on building a comprehensive performance management strategy that combines proper monitoring, proactive capacity planning, and continuous optimization of your Airflow workflows.

In the next post, we discuss capacity planning and the steps you need to perform before adding additional DAGs in your environment so that you can plan for the additional load and make sure you have enough headroom.

To get started, visit the Amazon MWAA product page and the Performance tuning for Apache Airflow on Amazon MWAA page.

If you have questions or want to share your MWAA scaling experiences, leave a comment below.

About the authors

Boyko Radulov

Boyko Radulov

Boyko is a Senior Cloud Support Engineer at Amazon Web Services (AWS), Amazon MWAA and AWS Glue Subject Matter Expert. He works closely with customers to build and optimize their workloads on AWS while reducing the overall cost. Beyond work, he is passionate about sports and travelling.

Kamen Sharlandjiev

Kamen Sharlandjiev

Kamen is a Principal Big Data and ETL Solutions Architect, Amazon MWAA and AWS Glue ETL expert. He’s on a mission to make life easier for customers who are facing complex data integration and orchestration challenges. His secret weapon? Fully managed AWS services that can get the job done with minimal effort. Follow Kamen on LinkedIn to keep up to date with the latest Amazon MWAA and AWS Glue features and news.

Venu Thangalapally

Venu Thangalapally

Venu is a Senior Solutions Architect at AWS, based in Chicago, with deep expertise in cloud architecture, data and analytics, containers, and application modernization. He partners with financial service industry customers to translate business goals into secure, scalable, and compliant cloud solutions that deliver measurable value. Venu is passionate about using technology to drive innovation and operational excellence.

Harshawardhan Kulkarni

Harshawardhan Kulkarni

Harshawardhan is a Partner Technical Account Manager at AWS, Amazon MWAA Subject Matter Expert. Based in Dublin Ireland, he partners with Enterprise Customers across EMEA to help navigate complex workflows and orchestration challenges while ensuring best practice implementation. Outside of work, he enjoys traveling and spending time with his family.

Andrew McKenzie

Andrew McKenzie

Andrew is a Data Engineer and Educator who uses deep technical expertise from his time at AWS. As a former Amazon MWAA Subject Matter Expert, he now focuses on building data solutions and teaching data engineering best practices.

Access control with IAM Identity Center session tags

Post Syndicated from Rashmi Iyer original https://aws.amazon.com/blogs/security/access-control-with-iam-identity-center-session-tags/

As organizations expand their Amazon Web Services (AWS) footprint, managing secure, scalable, and cost-efficient access across multiple accounts becomes increasingly important. AWS IAM Identity Center offers a centralized, unified solution for managing workforce access to AWS accounts. It simplifies authentication, enhances security, and provides a seamless user sign-in experience to AWS services across diverse environments.

By combining IAM Identity Center permission sets with session tags, organizations can unlock powerful capabilities for fine-grained access control and resource optimization. You can use session tags to pass dynamic attributes from your external identity provider into AWS, enabling more context-aware permissions and better cost visibility. This integration makes it possible to use advanced AWS features such as AWS Glue usage profiles and AWS Systems Manager Session Manager run as to enforce fine-grained access control, so that administrators can dynamically map permissions and runtime configurations based on user attributes passed during federated access.

In this post, I demonstrate how session tags derived from directory group attributes in Microsoft Entra ID can deliver functionality equivalent to AWS Identity and Access Management (IAM) role tags. Using role tags, you can implement attribute-based access control (ABAC) using IAM Identity Center, while maintaining centralized and efficient access management. To demonstrate this, you can configure an AWS Glue usage profile, as described in Introducing AWS Glue usage profiles for flexible cost control, where session tags can be passed through Identity Center and an external identity provider like Microsoft Entra ID. This approach is extensible to other AWS services such as AWS Systems Manager Session Manager (run as) and can also be used with other identity providers.

User authentication and IAM Identity Center Federation flow

The following figure shows the architecture and workflow of the solution.

Figure 1 – User authentication and federation flow between Microsoft Entra and AWS

Figure 1 – User authentication and federation flow between Microsoft Entra and AWS

The user authentication and federation flow includes the following steps:

  1. User accesses application using a browser.
  2. The enterprise application (configured in Azure) initiates authentication.
  3. Microsoft Entra ID handles sign-in.
  4. Users and groups are managed in Entra ID.
  5. A SAML trust is established between Entra ID and IAM Identity Center.
  6. SCIM provisioning syncs users and groups from Entra ID to AWS.
  7. Synced users and groups appear in Identity Center.
  8. Session tags are passed during SAML authentication.
    • Entra ID can send user attributes (department, role, cost center, project ID, and so on) as SAML attributes.
    • Identity Center consumes these as session tags, which are used for fine-grained access control and attribute-based access control inside AWS.
  9. Admins define permission sets for users and groups in Identity Center.
  10. Users get federated access to AWS using their Entra ID credentials.
  11. Users sign in through AWS Management Console or AWS Command Line Interface (AWS CLI) using those permissions.
  12. Access is granted to specific AWS accounts under AWS Organizations.

Prerequisites

To follow the steps in this post, you need the following prerequisites:

  1. An organization instance of IAM Identity Center enabled.
  2. A Microsoft Entra ID tenant. For more information, see Quickstart: Create a new tenant in Microsoft Entra ID.
  3. Access to an external identity provider such as Microsoft Entra ID to federate users into AWS. You can enable federated access between Microsoft Entra ID and IAM Identity Center by completing the steps in Configure SAML and SCIM with Microsoft Entra ID and IAM Identity Center. They include configuring SAML and SCIM integration between the two systems, testing the SAML connection to help ensure authentication is functioning correctly, and enabling SCIM synchronization to automate user and group provisioning.

Solution implementation

With the prerequisites in place, you’re ready to configure access control through IAM Identity center tags by using the following steps.

  1. Create an AWS Glue usage profile as described in Introducing AWS Glue usage profiles for flexible cost control in Create an AWS Glue usage profile. For the purposes of this post, create a profile named developer.
    1. On the AWS Management Console for AWS Glue, choose Cost management in the navigation pane.
    2. Choose Create usage profile.
    3. For Usage profile name, enter developer.
    4. Under Customize configurations for jobs, for Number of workers, for Default, enter 20.
    5. For Default worker type, select G.1X.
    6. For Allowed worker types, select G.1X, G.2X, G.4X, and G.8X.
    7. For Customize configurations for sessions, configure the same values.
    8. Choose Create usage profile.
    Figure 2 – Glue usage profile creation on the console

    Figure 2 – Glue usage profile creation on the console

  2. Create a custom permission set instead of using predefined ones. Attach the following AWS Managed Policies to the custom permission set:
    • AWSGlueConsoleFullAccess
    • IAMReadOnlyAccess

    Note: For fine-grained access control, you can create custom permission sets by combining AWS managed, customer managed, and inline policies in IAM. In this post, you use AWS managed policies with intentionally broad permissions for simplicity. In production, always follow the principles of least privilege and scope permissions appropriately.

    By default, when you create a permission set, the permission set isn’t provisioned (used in any AWS accounts). To provision a permission set in an AWS account, you must assign IAM Identity Center access to users or groups in the account and then apply the permission set to those users and groups. For more information, see Assign user or group access to AWS accounts.

  3. Configure user attributes in Microsoft Entra ID for access control in IAM Identity Center as described in Step 5 of Configure SAML and SCIM with Microsoft Entra ID and IAM Identity Center to set up ABAC. Add claim conditions for attribute mapping based on Entra ID group membership. Assign the developer value for users in a corresponding group. This enables logic such as Users in this group receive this profile or All users receive this profile. When using an AWS Glue profile and when making API calls to create AWS Glue resources, admins need to tag the user or role with glue:UsageProfile as the key and the profile name as the value.
  4. Next, sign in to the enterprise application that you created in the previous step, which has SCIM and SAML connections set up to IAM Identity Center:
    1. Sign in to Azure.
    2. Choose Enterprise applications.
    3. Select the application that you created
      Figure 3 – An enterprise application created in Microsoft Entra ID

      Figure 3 – An enterprise application created in Microsoft Entra ID

  5. When you’re signed in to your application, select Manage and then Single sign-on in the navigation pane, then select Attributes & Claims.
    Figure 4 – Attributes & Claims section in Microsoft Entra ID

    Figure 4 – Attributes & Claims section in Microsoft Entra ID

  6. Configure the key value pair that will used as session tags by selecting Add new claim.
    Figure 5 – Configuring attributes by adding a new claim

    Figure 5 – Configuring attributes by adding a new claim

  7. For Name, enter AccessControl:<AttributeName>. Replace <AttributeName> with the name of the attribute you are expecting in IAM Identity Center. For this example, use AccessControl:glue:UsageProfile.
  8. In Claim conditions set the following:
    • User type, select Members
    • Source, select Attribute.
    • Value, enter developer (without quotation marks).
    Figure 6 – Attribute claim addition in Microsoft Entra using group membership

    Figure 6 – Attribute claim addition in Microsoft Entra using group membership

It’s important to note that the tags are being assigned based on group membership in Microsoft Entra ID. This approach lets you manage access and configuration dynamically without needing to set tags individually for each user. By assigning the tag to a Microsoft Entra ID group, anyone signing in to IAM Identity Center and who is in that group will automatically have the tag value applied to their session.

Test the solution

Now that the required configuration is complete, test the setup using the developer usage profile created as part of the Solution implementation section. Sign in as your user through Microsoft Entra ID using https://myapps.microsoft.com/ and verify the job creation using the following steps mentioned.

To verify successful job creation:

  1. Open the AWS Glue console using the developer usage profile.
  2. In the navigation pane, choose ETL jobs.
  3. Select Script editor, then choose Create script.
  4. Create a new job using the values you want to validate.

The green banner at the top of the screen should say Successfully updated job.

Figure 7 – Successful AWS Glue job creation with configured parameters for the <em>developer</em> usage profile” width=”678″ height=”864″ class=”size-full wp-image-41907″></p>
<p id=Figure 7 – Successful AWS Glue job creation with configured parameters for the developer usage profile

Validation using AWS CloudTrail

Examine the AssumeRoleWithSAML event using AWS Cloudtrail. Use the following steps to verify the sequence of events.

  1. Navigate to the CloudTrail console.
  2. Select Event history.
  3. In the Lookup attributes dropdown, select Event name.
  4. Set the event name to AssumeRoleWithSAML.
  5. Open a relevant event and inspect the requestParameters section.
  6. Confirm that the expected session tags appear under PrincipalTags.
Figure 8 – ABAC tags passed during the role assumption

Figure 8 – ABAC tags passed during the role assumption

Using session tags for other use cases

The concepts discussed in this post can be extended to configure AWS Systems Manager Session Manager Run As support for federated users using session tags. By default, Session Manager launches sessions using a system-generated ssm-user account. For Linux instances, you can optionally configure sessions to run as a specific OS-level user through Session Manager preferences. You can configure your identity provider to pass the user attribute (AccessControl: SSMSessionRunAs and name of an OS user account for the key value during federation and the session will be tagged using the attribute value.

Clean up

To avoid incurring future charges, delete any resources created during this walkthrough if they’re no longer needed:

  1. Remove the IAM Identity Center instance and clean up the associated enterprise application in Microsoft Entra.
  2. Delete the AWS Glue usage profile.
  3. Remove any other AWS resources you provisioned for testing the solution.

Conclusion

In this post, you learned how to federate access to AWS using AWS IAM Identity Center and SAML 2.0 identity providers like Microsoft Entra ID, enabling a secure, scalable, and centralized approach to managing user access across multiple AWS accounts. By using permission sets, reserved IAM roles, and session tags, organizations can implement fine-grained ABAC without the complexity of managing individual IAM users or static roles.

As cloud environments become more complex, adopting modern identity federation and ABAC through IAM Identity Center helps security teams maintain control while providing users with seamless, context-aware access to the resources they need.

Resources

If you have feedback about this post, submit comments in the Comments section below.

Rashmi Iyer

Rashmi Iyer

Rashmi is a Senior Solutions Architect at AWS, supporting financial services enterprises in building secure, resilient, and scalable cloud architectures while ensuring compliance with industry best practices. With over 15 years of experience in the private telco cloud, she has designed and architected complex telecom solutions, specializing in the packet core domain, the backbone of mobile data networks.

Using Apache Sedona with AWS Glue to process billions of daily points from a geospatial dataset

Post Syndicated from Ruan Roloff original https://aws.amazon.com/blogs/big-data/using-apache-sedona-with-aws-glue-to-process-billions-of-daily-points-from-a-geospatial-dataset/

Data strategy can use geospatial data to provide organizations with insights for decision-making and operational optimization. By incorporating geospatial data (such as GPS coordinates, points, polygons and geographic boundaries), businesses can uncover patterns, trends, and relationships that might otherwise remain hidden across multiple industries, from aviation and transportation to environmental studies and urban planning. Processing and analyzing this geospatial data at scale can be challenging, especially when dealing with billions of daily observations.

In this post, we explore how to use Apache Sedona with AWS Glue to process and analyze massive geospatial datasets.

Introduction to geospatial data

Geospatial data is information that has a geographic component. It describes objects, events, or phenomena along with their location on the Earth’s surface. This data includes coordinates (latitude and longitude), shapes (points, lines, polygons), and associated attributes (such as the name of a city or the type of road).

Key types of geospatial geometries (and examples of each in parentheses) include:

  • Point – Represents a single coordinate (a weather station).
  • MultiPoint – A collection of points (bus stops in a city).
  • LineString – A series of points connected in a line (a river or a flight path).
  • MultiLineString – Multiple lines (multiple flight routes).
  • Polygon – A closed area (the boundary of a city).
  • MultiPolygon – Multiple polygons (national parks in a country).

Geospatial datasets come in different formats, each designed to store and represent different types of geographic information. Common formats for geospatial data are vector formats (Shapefile, GeoJSON), raster formats (GeoTIFF, ESRI Grid), GPS formats (GPX, NMEA), web formats (WMS, GeoRSS) among others.

Core concepts of Apache Sedona

Apache Sedona is an open-source computing framework for processing large-scale geospatial data. Built on top of Apache Spark, Sedona extends Spark’s capabilities to handle spatial operations efficiently. At its core, Sedona introduces several key concepts that enable distributed spatial processing. These include Spatial Resilient Distributed Datasets (SRDDs), which allow for the distribution of spatial data across a cluster, and Spatial SQL, which provides a familiar SQL-like interface for spatial queries. Some of the core capabilities of Apache Sedona are:

  • Efficient spatial data types like points, lines and polygons.
  • Spatial operations and functions such as ST_Contains (check if point is inside of a polygon), ST_Intersects (check if point is inside of a polygon), ST_H3CellIDs (geospatial indexing system developed by Uber, return the H3 cell ID(s) that contain the given point at the specified resolution).
  • Spatial joins to combine different spatial datasets.
  • Integration with Spark SQL (geospatial functions to run spatial SQL queries).
  • Spatial indexing techniques, such as quad-trees and R-trees, to optimize query performance.

For more information about the functions available in Apache Sedona, visit the official Sedona Functions documentation.

Use case

This use case consists of a global air traffic visualization and analysis platform that processes and displays real-time or historical aircraft tracking data on an interactive world map. Using unique aircraft identifiers from the International Civic Aviation Organization (ICAO), the system ingests trajectory records containing information such as geographic position (latitude and longitude), altitude, speed, and flight direction, then transforms this raw data into two complementary visual layers. The Flight Tracks Layer plots the routes traveled by each aircraft individually, allowing for the analysis of specific trajectories and navigation patterns. The Flight Density Layer uses hexagonal spatial indexing (H3) to aggregate and identify regions of higher air traffic concentration worldwide, revealing busy air corridors, aviation hubs, and high-density flight zones.

The dataset used for this use case is historical flight tracker data from ADSB.lol. ADSB.lol provides unfiltered flight tracker with a focus on open data. Data is also freely available via the API. The data contains a file per aircraft, a JSON gzip file containing the data for that aircraft for the day.

This is a JSON trace file format sample:

{
    icao: "0123ac", // hex id of the aircraft
    timestamp: 1609275898.495, // unix timestamp in seconds since epoch (1970)
    trace: [
        [ seconds after timestamp,
            lat,
            lon,
            altitude in ft or "ground" or null,
            ground speed in knots or null,
            track in degrees or null, (if altitude == "ground", this will be true heading instead of track)
            flags as a bitfield: (use bitwise and to extract data)
                (flags & 1 > 0): position is stale (no position received for 20 seconds before this one)
                (flags & 2 > 0): start of a new leg (tries to detect a separation point between landing and takeoff that separates flights)
                (flags & 4 > 0): vertical rate is geometric and not barometric
                (flags & 8 > 0): altitude is geometric and not barometric
             ,
            vertical rate in fpm or null,
            aircraft object with extra details or null,
            type / source of this position or null,
            geometric altitude or null,
            geometric vertical rate or null,
            indicated airspeed or null,
            roll angle or null
        ],
    ]
}

For this use case, this is a simplified schema of the dataset after processing:

  • icao - Unique aircraft identifier
  • timestamp - Epoch timestamp of the observation (converted to readable format)
  • trace.lat / trace.lon - Latitude and longitude of the aircraft
  • trace.altitude - Aircraft altitude
  • trace.ground_speed - Ground speed
  • geometry - Geospatial geometry of the observation point (Point)

Solution overview

This solution enables aircraft tracking and analysis. The data can be visualized on maps and used for aviation management and safety applications. The process begins with data acquisition, extracting the compressed JSON files from TAR archives, then transforms this raw data into geospatial objects, aggregating them into H3 cells for efficient analysis. The processed data schema includes ICAO aircraft identifiers, timestamps, latitude/longitude coordinates, and derived fields such as H3 cell identifiers and point counts per cell. This structure allows detailed tracking of individual flights and aggregate analysis of traffic patterns. For visualization, you can generate density maps using the H3 grid system and create visual representations of individual flight tracks. The architecture data flow is as follows:

  • Data ingestion – Aircraft observation data stored as JSON compressed files in Amazon Simple Storage Service (Amazon S3).
  • Data processing – AWS Glue jobs using Apache Sedona for geospatial processing.
  • Data visualization – Spark SQL with Sedona’s spatial functions to extract insights and export data to visualize the information in a map on Kepler.gl.

The following figure illustrates this solution.

AWS architecture diagram showing a geospatial data processing pipeline.

Prerequisites

You will need the following for this solution:

Solution walkthrough

From now on, executing the next steps will incur costs on AWS. This step-by-step walkthrough demonstrates an approach to processing and analyzing large-scale geospatial flight data using Apache Sedona and Uber’s H3 spatial indexing system, using AWS Glue for distributed processing and Apache Sedona for efficient geospatial computations. It explains how to ingest raw flight data, transform it using Sedona’s geospatial functions, and index it with H3 for optimized spatial queries. Finally, it also demonstrates how to visualize the data using Kepler.gl. For data processing, it is possible to use both Glue scripts and Glue notebooks. In this post, we will focus only on Glue scripts.

Upload the Apache Sedona libraries to Amazon S3

  1. Open your OS terminal command line.
  2. Create a folder to download the Sedona libraries and name it jar.
    
    	# Create a directory for the Sedona libraries (JARs files)
    	mkdir jar
    	# Go to the folder JARs folder
    	cd jar
    	
  3. Download the Apache Sedona libraries.
    
    	# Download required Sedona libraries (JARs files)
    	wget https://repo1.maven.org/maven2/org/apache/sedona/sedona-spark-shaded-3.5_2.12/1.7.1/sedona-spark-shaded-3.5_2.12-1.7.1.jar
    	wget https://repo1.maven.org/maven2/org/datasyslab/geotools-wrapper/1.7.1-28.5/geotools-wrapper-1.7.1-28.5.jar
    	
  4. Upload the Sedona libraries (JARs files) to Amazon S3. In this example, we use the S3 path s3://aws-blog-post-sedona-artifacts/jar/.
    
    	# Upload the JARs files to Amazon S3 bucket
    	aws s3 cp . s3://blog-sedona-artifacts-<account_number>-<aws_region>/jar/ --recursive
    	
  5. Your Amazon S3 folder should now look similar to the following image:

Amazon S3 console screenshot displaying the jar folder contents in blog-sedona-artifacts bucket.

Download and upload the geospatial data to Amazon S3

  1. Open your OS terminal command line.
  2. Create a folder to download the flight files and name it adsb_dataset.
    		# Create a directory for download the geospatial flight files
    		mkdir adsb_dataset
    		# Go to the folder for geospatial flight files
    		cd adsb_dataset
    	
  3. Download the flight files data from adsblol GitHub repository.
    	# Download the geospatial flight files in the folder created
    	wget https://github.com/adsblol/globe_history_2025/releases/download/v2025.05.29-planes-readsb-prod-0tmp/v2025.05.29-planes-readsb-prod-0tmp.tar.aa
    	wget https://github.com/adsblol/globe_history_2025/releases/download/v2025.05.29-planes-readsb-prod-0tmp/v2025.05.29-planes-readsb-prod-0tmp.tar.ab
    	
  4. Extract the flight files.
    	# Combine the two the tar files together
    	cat v2025.05.29* >> combined.tar
    	# Extract the json flight files from the tar file
    	tar xf combined.tar
    	
  5. Copy the flight files to Amazon S3. In this case, we are using the S3 folder: s3://blog-sedona-nessie-<account_number>-<aws_region>/raw/adsb-2025-05-28/traces/.
    	# Copy the json flight files to Amazon S3
    	aws s3 cp ./traces/ s3://blog-sedona-nessie-<account_number>-<aws_region>/raw/adsb-2025-05-28/traces/ --recursive
    	
  6. Your Amazon S3 folder should now look similar to the following image.

Amazon S3 console showing JSON trace files in the path raw/adsb-2025-05-28/traces/00/.

Create an AWS Glue job and set up the job

Now, we are ready to define the AWS Glue job using Apache Sedona to read the geospatial data files. To create a Glue job:

  1. Open the AWS Glue console.
  2. On the Notebooks page, choose Script editor.

AWS Glue Studio jobs creation interface showing three job creation methods: Visual ETL with data flow interface, Notebook for interactive coding, and Script editor for code authoring

  1. On the Script screen, for the engine, choose Spark, then select the option Upload script.
  2. Choose Choose file. Find the process_sedona_geo_track.py file, then choose Create script.

Script creation dialog box with Spark engine selected. Upload script option is active, showing successfully uploaded file process_sedona_geo_track.py.

  1. Rename the job from Untitled to process_sedona_geo_track.
  2. Choose Save.
  3. Now, let’s set up the AWS Glue job. Choose Job Details.
  4. Choose the IAM Role created to be used with Glue. For this example, we use blog-glue.
  5. Set the Glue version to Glue 5.0 and the Worker type as needed. For this example, G.1X is sufficient, but we use G.2X to speed up processing.

AWS Glue job details configuration page for process_sedona_geo_track.

  1. Now, let’s import the libraries for Apache Sedona.
  2. In the Dependent JARs path, type the path of the JAR files for Apache Sedona that you uploaded in the preceding steps. For this example, we used s3://blog-sedona-artifacts-<account_number>-<aws_region>/jar/sedona-spark-shaded-3.5_2.12-1.7.1.jar,s3://blog-sedona-artifacts-<account_number>-<aws_region>/jar/geotools-wrapper-1.7.1-28.5.jar
  3. In Additional Python modules path, enter the modules for Apache Sedona: apache-sedona==1.7.1,geopandas==0.13.2,shapely==2.0.1,pyproj==3.6.0,fiona==1.9.5,rtree==1.2.0

ob libraries configuration section showing Dependent JARs path pointing to S3 bucket.

  1. In the Job parameters section, in the Key field, type —BUCKET_NAME. For its Value, enter your bucket name. In this example, ours is blog-sedona-nessie-<account_number>-<aws_region>.

ob parameters configuration interface showing key-value pair with --BUCKET_NAME parameter.

  1. Choose Save.

Processing the geospatial flights data

Before we run the job, let’s understand how the code works. First, import the Apache Sedona libraries:

import json 
import gzip 
from sedona.spark import SedonaContext

Next, initialize the Sedona context using an existing Spark session:

sedona = SedonaContext.create(spark)

After that, create a function for handling compressed JSON data:

def parse_gzip_json(byte_content):
        try:
            decompressed = gzip.decompress(byte_content)
            return json.loads(decompressed.decode('utf-8'))
        except Exception as e:
            print(f"Error during gzip parse: {str(e)}")
            return None

Add a function to transform raw tracking data into a structured format suitable for a valid coordinates process:

def flatten_records(json_obj):
    records = []
    if "trace" in json_obj and isinstance(json_obj["trace"], list):
        for point in json_obj["trace"]:
            if len(point) >= 3:
                lat, lon = float(point[1]), float(point[2])
                if -90 <= lat <= 90 and -180 <= lon <= 180:
                    records.append(Row(
                        icao=json_obj.get("icao", None),
                        timestamp=json_obj.get("timestamp", None),
                        lat=lat,
                        lon=lon
                    ))
    return records

The flat_rdd variable applies these functions to the structured data from the original gzipped JSON. Each element in this RDD is a Row object representing a single data point from an aircraft’s trace, with fields for ICAO, timestamp, latitude, and longitude.

flat_rdd = raw_rdd.map(lambda x: parse_gzip_json(x[1])).filter(lambda x: x is not None).flatMap(flatten_records)

The ADSB trace files contain a deeply nested JSON structure where the trace field holds an array of mixed-type arrays, compressed in Gzip format. For this specific case, developing a UDF represented one of the most practical and efficient solutions. Since Gzip is a non-splittable format, Spark is unable to parallelize processing, constraining both methods to a single worker per file and processing the data multiple times across JVM decompression, full JSON parsing, and subsequent re-parsing operations. The UDF bypasses all of this by reading raw bytes and doing everything in a single Python pass: decompress → parse → extract → validate, returning only the small set of needed fields directly to Spark.

The Spark SQL query processes geographic trace data using the H3 hexagonal grid system, converting point data into a regularized hexagonal grid that can help identify areas of high point density. A resolution of 5 was adopted, producing hexagons of approximately 253 km² (roughly the same size as the city of Edinburgh, Scotland, which is approximately 264 km²), for its ability to effectively capture route density patterns at the city and metropolitan level.

h3_traces_df = spark.sql("""
WITH base_h3 AS (
    SELECT
        ST_H3CellIDs(geometry, 5, false)[0] AS h3_index,
        lat,
        lon
    FROM traces
)
SELECT
    COUNT(*) AS num, -- Count points in each H3 cell
    h3_index,
    AVG(lon) AS center_lon,
    AVG(lat) AS center_lat
FROM base_h3
GROUP BY h3_index
""")

Finally, this code prepares the datasets for visualization purposes. The first dataset is based on the aircraft unique identifier. The complete dataset for a single day can contain more than 80 million data points. A random sampling rate of 0.1% was applied, which proves sufficient to illustrate route density patterns without overwhelming the Kepler.gl browser renderer. The second dataset aggregates trace points into hexagonal spatial cells (result from the query above).

points_viz_sampled = df_points.select(
    col("icao"), # Aircraft unique identifier (24-bit address)
    col("timestamp").cast("double").alias("timestamp"),
    col("lat").cast("double").alias("lat"),
    col("lon").cast("double").alias("lon")
).sample(False, 0.001)

h3_viz_csv = h3_traces_df.select(
    col("num").alias("point_count"),
    col("h3_index").cast("string").alias("h3_index"),
    col("center_lon"),
    col("center_lat")
)

Now that we understand the code, let’s run it.

  1. Open the AWS Glue console.
  2. On the ETL jobs >> Notebooks page, choose the job name process_sedona_geo_track.
  3. Choose Run.

Python script editor showing import statements for process_sedona_geo_track job.

  1. Now, it is possible to monitor the job by choosing the Runs tab.
  2. It may take a few minutes to run the entire job. It took nearly 8 minutes to process approximately 2.50 GB (67,540 compressed files) with 20 DPUs. After the job is processed, you should see your job with the status Succeeded.

Job runs monitoring dashboard showing successful execution on June 5, 2025, running from 12:28:03 to 12:36:37 with 8 minutes 19 seconds duration.

Now your data should be saved for a preview visualization demo in a folder named s3://blog-sedona-nessie-<account_number>-<aws_region>/visualization/.

Performance insights

The workload characterization of this job reveals a CPU-intensive profile, primarily because of the processing of small binary files with GZIP compression and subsequent JSON parsing. Given the inherent nature of this pipeline, which includes Python UDF serialization and partial single-partition write stages, linear scaling does not yield proportional performance gains. The following table presents an analysis of AWS Glue configurations, evaluating the trade-off between computational capacity, execution duration, and associated costs:

Duration Capacity (DPUs) Worker type Glue version Estimated Cost*
10 m 7 s 32 DPUs G.1X 5 $2.34
11 m 50 s 10 DPUs G.1X 5 $0.88
19 m 7 s 4 DPUs G.1X 5 $0.59
8 m 19 s 20 DPUs G.2X 5 $1.32

*Estimated Cost = DPUs x Duration (hours) x $0.44 per DPU-hour (us-east-1)

Visualizing and analyzing geospatial data with Kepler.gl

Kepler.gl is an open-source geospatial analysis tool developed by Uber with code available at Github. Kepler.gl is designed for large-scale data exploration and visualization, offering multiple map layers, including point, arc, heatmap, and 3D hexagon. It supports various file formats like CSV, GeoJSON, and KML. In this use case, we will use Kepler.gl to present interactive visualizations that illustrate flight patterns, routes, and densities across global airspace.

Downloading the geospatial files

Before we can view the graph, we will need to download the flight files to our local machine, unzip them, and rename them (to make it easier to identify the files).

  1. Open your OS terminal command line.
  2. Create the folders to download the data processed in the steps before. In this case, we create kepler and kepler_csv.
    	#create kepler folders: first folder is to download the files,
    	#second folder is to organize the files to use in the next step
    	mkdir kepler
    	mkdir kepler_csv
    	
  3. Replace the bracketed variables with your account and directory information, then download all the CSV files.
    	#copy the files from Amazon S3 to local machine
    	aws s3 cp s3://blog-sedona-nessie-<account_number>-<aws_region>/visualization/ /<user_directory>/kepler --recursive
    	
  4. Extract the files, rename them, and move them to another folder.
    	# Extract the files processed by Spark and Sedona
    	gzip -d ./kepler/kepler_h3_density/*.gz
    	gzip -d ./kepler/kepler_track_points_sample/*.gz
    	
    	# Rename the Spark output files to more readable names
    	cd ./kepler/kepler_h3_density/
    	ls
    	mv part-00000-*.csv kepler_h3_density.csv
    	cd ..
    	
    	cd ./kepler/kepler_track_points_sample/
    	ls
    	mv part-00000-*.csv kepler_track_points_sample.csv
    	cd ..
    	
    	# Ensure the output folder exists
    	mkdir -p ../kepler_csv
    	
    	# Copy the renamed CSV files to the folder that will be used as input in kepler.gl
    	cp ./kepler/kepler_h3_density/*.csv ../kepler_csv
    	cp ./kepler/kepler_track_points_sample/*.csv ../kepler_csv
    	
  5. Your kepler_csv folder should look similar to the return of the command below.
    	#list the files in the kepler_csv directory
    	ls -l
    	total 11684
    	-rw-rw-r-- 1 ec2-user ec2-user 8630110 Jun 12 14:47 kepler_h3_density.csv
    	-rw-rw-r-- 1 ec2-user ec2-user 3331763 Jun 12 14:47 kepler_track_points_sample.csv
    	

Visualizing the data in a graph

Now that you have saved the data to your local machine, you can analyze the flight data through interactive map graphics. To import the data into the Kepler.gl web visualization tool:

  1. Open the Kepler.gl Demo web application.
  2. Load data into Kepler.gl:
    1. Choose Add Data in the left panel.
    2. Drag and drop both CSV files (flight_points and h3_density) into the upload area.
    3. Confirm that both datasets are loaded successfully.
  3. Delete all layers.
  4. Create the Flight Density Layer:
    1. Choose Add Layer in the left panel.
    2. In Basic, choose H3 as the layer type, then add the following configuration:
      1. Layer Name: Flight Density
      2. Data Source: kepler_h3_density.csv
      3. Hex ID: h3_index
    3. In the Fill Color section:
      1. Color: point_count
      2. Color Scale: Quantile.
      3. Color Range: Choose a blue/green gradient.
    4. Set Opacity to 0.7.
    5. In the Coverage section, set it to 0.9.
  5. Create the Flight Tracks Layer:
    1. Choose Add Layer in the left panel.
    2. In Basic, choose Point as the layer type, then add the following configuration:
      1. Layer Name: Flight Tracks
      2. Data Source: kepler_track_points_sample.csv
      3. Columns:
        1. Latitude: lat
        2. Longitude: lon
    3. In the Fill Color section:
      1. Solid Color: Orange
      2. Opacity: 0.3
    4. Set the Point’s Radius to 1
  6. The layers should look similar to the following figure.

Kepler.gl layer configuration panel for Flight Density H3 layer using kepler_h3_density.csv data source.

  1. The graph visualization should now show flight density through color-coded hexagons, with individual flight tracks visible as orange points:

Kepler.gl interactive map visualization displaying global flight density heatmap. High-density areas shown in yellow over North America, particularly the United States.

There you go! Now that you have knowledge about geospatial data and have created your first use case, take the opportunity to do some analysis and learn some interesting facts about flight patterns.

It is possible to experiment with other interesting types of analysis in Kepler.gl, such as Time Playback.

Clean up

To clean up your resources, complete the following tasks:

  1. Delete the AWS Glue job process_sedona_geo_track.
  2. Delete content from the Amazon S3 buckets: blog-sedona-artifacts-<account_number>-<aws_region> and blog-sedona-nessie-<account_number>-<aws_region>.

Conclusion

In this post, we showed how processing geospatial data can present significant challenges due to its complex nature (from big data to data structure format). For this use case of flight trackers, it involves vast amounts of information across multiple dimensions such as time, location, altitude, and flight paths, however, the combination of Spark’s distributed computing capabilities and Sedona’s optimized geospatial functions helps overcome those challenges. The spatial partitioning and indexing features of Sedona, coupled with Spark’s framework, enable us to perform complex spatial joins and proximity analyses efficiently, simplifying the overall data processing workflow.

The serverless nature of AWS Glue eliminates the need for managing infrastructure while automatically scaling resources based on workload demands, making it an ideal platform for processing growing volumes of flight data. As the volume of flight data grows or as processing requirements fluctuate, with AWS Glue, you can quickly adjust resources to meet demand, ensuring optimal performance without the need for cluster management.

By converting the processed results into CSV format and visualizing them in Kepler.gl, it is possible to create interactive visualizations that reveal patterns in flight paths, and you can efficiently analyze air traffic patterns, routes, and other insights. This end-to-end solution demonstrates how a modern data strategy in AWS with the support of open-source tools can transform raw geospatial data into actionable insights.


About the authors

Ruan

Ruan Roloff is a Lead GTM Specialist Architect for Analytics and AI at AWS. During his time at AWS, he was responsible for the data journey and AI product strategy of customers across a range of industries, including finance, oil and gas, manufacturing, digital natives, public sector, and startups. He has helped these organizations achieve multi-million dollar use cases. Outside of work, Ruan likes to assemble and disassemble things, fish on the beach with friends, play SFII, and go hiking in the woods with his family.

Lucas

Lucas Vitoreti is a ProServe Data & Analytics Specialist at AWS with 12+ years in the data domain. Architects and delivers solutions for data warehouses, lakes, lakehouses, and meshes, helping organizations transform their data strategies and achieve business outcomes. Expertise in scalable data architectures and guiding data-driven transformations. He balances professional life with weightlifting, music, and family time.

Denys

Denys Gonzaga is a ProServe Consultant at AWS, he is an experienced professional with over 15 years of working across multiple technical domains, with a strong focus on development and data analytics. Throughout his career, he has successfully applied his skills in various industries, including aerospace, finance, telecommunications, and retail. Outside of AWS, Denys enjoys spending time with his family and playing video games.

Building unified data pipelines with Apache Iceberg and Apache Flink

Post Syndicated from Nikhil Jha original https://aws.amazon.com/blogs/big-data/building-unified-data-pipelines-with-apache-iceberg-and-apache-flink/

You can process real-time data from your data lake with Amazon Managed Service for Apache Flink without maintaining two separate pipelines. Yet many teams do exactly that, and the cost adds up fast. In this post, you build a unified pipeline using Apache Iceberg and Amazon Managed Service for Apache Flink that replaces the dual-pipeline approach. This walkthrough is for intermediate AWS users who are comfortable with Amazon Simple Storage Service (Amazon S3) and AWS Glue Data Catalog but new to streaming from Apache Iceberg tables.

The dual-pipeline problem

Traditional dual-pipeline architecture with separate batch and streaming paths, each with its own ingestion, processing, storage, and serving layers, processing the same source data independently.

This dual-pipeline approach creates three problems:

  • Double the infrastructure costs. You run and pay for two separate compute environments, two storage layers, and two sets of monitoring. For example, if you’re spending $10,000/month on separate streaming and batch infrastructure, a meaningful portion of that spend is pure duplication.
  • Data synchronization issues. Your batch and streaming consumers read from different copies of the data, processed at different times. When a transaction shows up in your real-time dashboard but not in your batch report (or vice versa), debugging the inconsistency takes hours.
  • Operational complexity. Two pipelines mean two deployment processes, two failure modes to monitor, and two sets of schema evolution to manage. Your team spends time reconciling systems instead of building features.

Where this pattern fits

Before diving into the implementation, consider whether streaming from your data lake is the right approach for your use case.

Streaming from Apache Iceberg tables works well when you need data available within seconds to minutes and you query recent data frequently, multiple times per hour. Common scenarios include:

  • Operational data stores — Stream customer profile updates to serve downstream applications like recommendation engines. When a customer updates their preferences, those changes reach your operational data store within seconds.
  • Fraud detection — Stream transactions for immediate analysis. Start with a 3-second monitor interval and adjust based on your detection accuracy needs.
  • Live dashboards — Power real-time analytics directly from your lake. This is the strongest starting point if you’re evaluating the approach for the first time, because the feedback loop is immediate and straightforward to validate.
  • Event-driven architectures — Trigger downstream processes based on data changes in your Apache Iceberg tables.

Batch processing remains more cost-effective when you process data once per day or less, or you primarily query historical data. Batch queries on Apache Iceberg tables cost less because they don’t require a continuous Apache Flink runtime.

How Apache Iceberg solves this

Apache Iceberg’s snapshot-based architecture removes the need for a separate streaming pipeline. Think of snapshots like Git commits for your data. Each time you write data to your Iceberg table, Iceberg creates a new snapshot that points to the new data files while preserving references to existing files. Apache Flink reads only the changes between snapshots (the new files that arrived after the last checkpoint), rather than scanning the entire table. Atomicity, Consistency, Isolation, Durability (ACID) transactions prevent your concurrent reads and writes from producing partial or inconsistent results. For example, if your batch extract, transform, and load (ETL) job is writing 10,000 records while your Flink application is reading, ACID transactions mean that your streaming query sees either the complete batch of 10,000 records or none of them, not a partial set that could skew your analytics.

The result is a single pipeline that handles both real-time and batch access from the same data, through the same storage layer, with the same schema.

Solution architecture

Your architecture uses four AWS services and one open source table format working together. The following diagram shows how these components connect, replacing the dual-pipeline pattern shown earlier with a single unified flow.

Unified pipeline architecture with data flowing from Amazon S3 through Apache Iceberg tables, with AWS Glue Data Catalog managing metadata, and Amazon Managed Service for Apache Flink consuming incremental snapshots for near real-time processing.

Your source data lands in Amazon S3 as Apache Iceberg table files. AWS Glue Data Catalog tracks the metadata and schema. When new data arrives, Apache Iceberg creates a new snapshot that your application detects. Your Flink application monitors these snapshots and processes new records incrementally, reading only the files that arrived after the last checkpoint, not the entire table.

You use four main components:

  • Amazon S3 — Foundational storage layer for your data lake
  • Data Catalog — Metadata and schema management for Apache Iceberg tables
  • Apache Iceberg — Table format with snapshot-based streaming capabilities
  • Amazon Managed Service for Apache Flink — Stream processing and incremental consumption

Important notices

Before implementing this solution, evaluate these risks for your environment:

  • Data security: Streaming from data lakes exposes data to additional processing systems. Classify your data before implementation—customer profile updates and transaction data typically contain personally identifiable information (PII) and treat them as confidential. Apply encryption at rest and in transit for confidential data. Key risks include unauthorized data access through misconfigured Amazon S3 bucket policies or overly permissive IAM roles. Mitigations: use the resource-scoped IAM policy and TLS-enforcing bucket policy provided in the Security section.
  • Data integrity: Misconfigured checkpoints or schema changes during streaming can lead to data inconsistency. Mitigations: enable exactly-once processing semantics and test schema evolution in a non-production environment first.
  • Compliance: Verify that real-time data processing meets your regulatory requirements. For workloads subject to HIPAA, confirm that you use HIPAA Eligible Services and have a Business Associate Agreement (BAA) with AWS. For PCI-DSS or GDPR workloads, review the relevant compliance documentation on the AWS Compliance page. Implement data retention policies that comply with your regulatory framework.
  • Cost: Nearly continuous streaming incurs ongoing compute costs. Monitor usage to avoid unexpected charges. Cost estimates in this post are based on pricing as of March 2026 and might change. Verify current pricing on the relevant AWS service pricing pages.
  • Operational: Pipeline failures might impact downstream systems. Implement monitoring and alerting before running in production.

Prerequisites

Before you begin, make sure that you have the following in place. This walkthrough assumes intermediate Python skills (comfortable with functions, error handling, and environment variables), basic Apache Flink concepts (streaming compared to batch processing), and basic AWS Identity and Access Management (AWS IAM) knowledge (creating roles and attaching policies). Plan for approximately 90–120 minutes, including setup, implementation, and testing. First-time setup might take longer as you download dependencies and configure AWS resources. Expected AWS costs: approximately $5–10 if you complete the walkthrough within 2 hours and clean up resources immediately afterward. The primary cost driver is Amazon Managed Service for Apache Flink runtime ($0.11/hour per Kinesis Processing Unit (KPU)). You can minimize costs by stopping your application when not in use.

  • An AWS account with AWS IAM permissions for: s3:GetObject, s3:PutObject, s3:ListBucket on your data bucket; glue:GetDatabase, glue:GetTable for catalog access; and flink:CreateApplication, flink:StartApplication for Amazon Managed Service for Apache Flink
  • An existing Amazon S3 bucket for your data lake
  • An AWS Glue Data Catalog database configured
  • Apache Flink 1.19.1 installed locally
  • Python 3.8 or later
  • Java 11 or a more recent version
  • AWS Command Line Interface (AWS CLI) configured with credentials (aws configure)

Required Java Archive (JAR) dependencies

You need multiple JAR files because your Flink application coordinates between different systems—Amazon S3 for storage, AWS Glue for metadata, Hadoop for file operations, and Apache Iceberg for the table format. Each JAR handles a specific part of this integration. Missing even one causes ClassNotFoundException errors at runtime.

  • iceberg-flink-runtime-1.19-1.6.1.jar — Core Apache Iceberg integration with Apache Flink
  • iceberg-aws-bundle-1.6.1.jar — AWS-specific Apache Iceberg functionality for Amazon S3 and AWS Glue
  • flink-s3-fs-hadoop-1.19.1.jar — Provides Apache Flink read and write access to Amazon S3
  • flink-sql-connector-hive-3.1.3_2.12-1.19.1.jar — Hive metastore connector for catalog compatibility
  • hadoop-common-3.4.0.jar — Core Hadoop libraries required by Apache Iceberg
  • flink-shaded-hadoop-2-uber-2.8.3-10.0.jar — Repackaged Hadoop dependencies that avoid version conflicts with Apache Flink
  • hadoop-hdfs-client-3.4.0.jar — Hadoop Distributed File System (HDFS) client libraries for file system operations
  • flink-json-1.19.1.jar — JSON format support for Apache Flink
  • hadoop-aws-3.4.0.jar — Hadoop integration with AWS services
  • hadoop-client-3.4.0.jar — Hadoop client libraries
  • aws-java-sdk-bundle-1.12.261.jar — AWS SDK for authentication and service access
jars = [
    "flink-s3-fs-hadoop-1.19.1.jar",
    "flink-sql-connector-hive-3.1.3_2.12-1.19.1.jar",
    "hadoop-common-3.4.0.jar",
    "flink-shaded-hadoop-2-uber-2.8.3-10.0.jar",
    "iceberg-flink-runtime-1.19-1.6.1.jar",
    "iceberg-aws-bundle-1.6.1.jar",
    "hadoop-hdfs-client-3.4.0.jar",
    "flink-json-1.19.1.jar",
    "hadoop-aws-3.4.0.jar",
    "hadoop-client-3.4.0.jar",
    "aws-java-sdk-bundle-1.12.261.jar"
]

Technical implementation

The sample code in this post is available under the MIT-0 license.This section walks you through building the streaming pipeline step by step. You create a single Python file, iceberg_streaming.py, with three functions that run in sequence. Your main() function calls them in order: set up the Apache Flink environment, register the Data Catalog, then start the streaming query.

Set up your Apache Flink environment

To prepare your Apache Flink environment:

  1. Download the required JAR files listed in the prerequisites section.
  2. Place the JAR files in a lib directory in your project folder.
  3. Configure your HADOOP_CLASSPATH environment variable to point to the lib directory.
  4. Create your streaming execution environment by adding the following function to iceberg_streaming.py:
def setup_environment():
    """Configure the Flink streaming runtime."""
    try:
        os.environ['HADOOP_CLASSPATH'] = os.path.join(os.getcwd(), 'lib', '*')
        env = StreamExecutionEnvironment.get_execution_environment()
        env.set_parallelism(1)
        settings = EnvironmentSettings.new_instance().in_streaming_mode().build()
        t_env = StreamTableEnvironment.create(env, settings)
        return t_env
    except Exception as e:
        print(f"Failed to initialize Flink environment: {e}")
        raise
  1. Verify your environment by running flink –version. If the command isn’t found, confirm that Apache Flink 1.19.1 is installed and that your PATH includes the Flink bin directory.

Configure AWS Glue Data Catalog

To connect your Flink application to Data Catalog:

  1. Open your iceberg_streaming.py file.
  2. Add the create_iceberg_source() function shown in the following section.
  3. Replace the placeholder values with your actual AWS resources before running. These values are static configuration strings, not user input — do not construct them from external or untrusted sources at runtime.
  4. Save the file.
def create_iceberg_source(t_env):
    """Register the AWS Glue Data Catalog as an Iceberg catalog."""
    try:
        catalog_sql = """
        CREATE CATALOG glue_catalog WITH (
            'type'='iceberg',
            'catalog-impl'='org.apache.iceberg.aws.glue.GlueCatalog',
            'warehouse'='s3://<example-data-lake-bucket>',
            'io-impl'='org.apache.iceberg.aws.s3.S3FileIO',
            'aws.region'='us-east-1',
            'hadoop-conf.fs.s3a.aws.credentials.provider'=
                'com.amazonaws.auth.DefaultAWSCredentialsProviderChain',
            'hadoop-conf.fs.s3a.endpoint'='s3.amazonaws.com',
            'property-version'='1'
        )
        """
        t_env.execute_sql(catalog_sql)
        t_env.use_catalog("glue_catalog")
        t_env.use_database("streaming_db")
    except Exception as e:
        print(f"Failed to configure Iceberg catalog: {e}")
        raise

Set up streaming logic

This function configures Apache Flink to monitor your Apache Iceberg table continuously and process new records as they arrive. Checkpointing runs every 10 seconds to track progress—if the job restarts, it resumes from the last checkpoint rather than reprocessing the entire table.Notice the monitor-interval parameter, it controls how frequently Apache Flink checks for new Apache Iceberg snapshots. A 3-second interval provides near real-time processing but generates approximately 1,200 Amazon S3 LIST API calls per hour (at $0.005 per 1,000 requests, roughly $0.04/month per table based on pricing as of March 2026). For less time-sensitive workloads, increase this to 30s to reduce API costs by 90%.Replace customer_events with the name of your Apache Iceberg table in Data Catalog:

def process_record(row):
    """Validate and process each record from the stream."""
    try:
        if row is None:
            raise ValueError("Received null row")
        required_fields = ["event_type", "timestamp"]
        for field in required_fields:
            if field not in row:
                raise ValueError(f"Missing required field: {field}")
        # Validate field types and content
        if not isinstance(row.get("event_type"), str) or len(row["event_type"]) > 256:
            raise ValueError("event_type must be a string under 256 characters")
        if not isinstance(row.get("timestamp"), (str, int)):
            raise ValueError("timestamp must be a string or integer")
        # Replace with your business logic
        print(f"Processing record: {row}")
    except ValueError as e:
        print(f"Validation error for record {row}: {e}")
    except Exception as e:
        print(f"Error processing record {row}: {e}")
def stream_data(t_env):
    """Start the streaming query and process results."""
    try:
        configuration = t_env.get_config().get_configuration()
        configuration.set_string("table.dynamic-table-options.enabled", "true")
        configuration.set_string("execution.checkpointing.interval", "10000")
        query = """
        SELECT * FROM customer_events /*+ OPTIONS(
            'streaming'='true',
            'monitor-interval'='3s',
            'table.exec.iceberg.cell-based-snapshot'='true'
        ) */
        """
        table_result = t_env.execute_sql(query)
        with table_result.collect() as results:
            for row in results:
                process_record(row)
    except Exception as e:
        print(f"Streaming query failed: {e}")
        raise

Putting it together

Your main() function calls the three steps in order:

def main():
    try:
        t_env = setup_environment()
        create_iceberg_source(t_env)
        stream_data(t_env)
    except Exception as e:
        print(f"Pipeline failed: {e}")
        raise
if __name__ == "__main__":
    main()

Run the pipeline locally:python iceberg_streaming.pyPackage the application and submit it to Amazon Managed Service for Apache Flink using the console or the AWS Command Line Interface (AWS CLI).

Running in production

Moving from a local test to a production deployment requires tuning four areas: performance, monitoring, cost, and security. This section covers the key decisions for each.

Performance tuning

Determine your latency requirements before tuning. For fraud detection, you need subsecond processing. For daily reporting dashboards, you can tolerate minutes of delay.

Partition pruning reduces the amount of data scanned per query. Proper partitioning can significantly reduce query times for time series data partitioned by date. To implement, create your Apache Iceberg table with partition columns (PARTITIONED BY (date_column) in your CREATE TABLE statement), then include partition filters in your WHERE clause: WHERE date_column >= CURRENT_DATE - INTERVAL '7' DAY.

Parallel processing matches your data volume and throughput requirements. For most workloads under 10,000 records per second, a parallelism of 1–4 is sufficient. Scale up incrementally and monitor backpressure metrics (indicators that data arrives faster than your pipeline processes it, causing queuing) to find the right setting.

Checkpoint tuning balances reliability and latency. Consider how much data you can afford to reprocess after a failure. If you process 1,000 records per second with 10-second checkpoints, a failure means reprocessing up to 10,000 records. When that’s acceptable, 10 seconds works well. For faster recovery or higher volumes, reduce to 5 seconds.

Resource allocation — Right-size your Apache Flink cluster to avoid over-provisioning. Monitor CPU and memory utilization during your initial runs and adjust task manager resources accordingly.

Monitoring

Configure your production deployment with the following checkpoint settings. These work well for moderate data volumes (up to 10,000 records per second), providing exactly-once processing semantics. This means that the pipeline processes each record exactly once, even if your application restarts. Adjust the checkpoint interval based on your latency requirements. Add this to your setup_environment() function after creating the table environment.

config_dict = {
    "execution.checkpointing.interval": "30000",
    "execution.checkpointing.mode": "EXACTLY_ONCE",
    "execution.checkpointing.timeout": "600000",
    "state.backend": "filesystem",
    "state.checkpoints.dir": "s3://<example-data-lake-bucket>/checkpoints"
}

Use Amazon CloudWatch to track checkpoint duration, records processed per second, and backpressure metrics. A 10-second checkpoint interval means writing state to Amazon S3 360 times per hour. For a 1 MB state size, that’s approximately 8.6 GB per day in checkpoint storage—at Amazon S3 Standard pricing of $0.023/GB, roughly $0.20/day or $6/month per application based on current pricing. If the checkpoint duration exceeds 50% of your interval, increase the interval or add parallelism.

Cost management

Use Amazon S3 Intelligent-Tiering for your Apache Iceberg data files, which typically have predictable access patterns after initial processing. Configure Apache Iceberg’s table expiration to automatically clean up early snapshots. This can reduce storage costs by an estimated 20–30%, though your results vary depending on write frequency and retention policies.

Right-size your Apache Flink resources based on actual throughput needs. Start with a minimal configuration and scale up based on observed backpressure and checkpoint duration metrics. Use Amazon Elastic Compute Cloud (Amazon EC2) Spot Instances where workload interruptions are acceptable, for example, in development and testing environments.

Set data retention policies on both your Apache Iceberg tables and checkpoint storage to avoid storing data longer than necessary.

Security

Security is a shared responsibility between you and AWS. AWS is responsible for the security of the cloud, including the hardware, software, networking, and facilities that run AWS services. You are responsible for security in the cloud, configuring access controls, encrypting data, and managing your application security. Apply these controls in priority order.

AWS IAM roles — Use AWS IAM roles with least-privilege access, scoped to specific resources. The following example policy restricts permissions to your data lake bucket and AWS Glue catalog:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": ["s3:GetObject", "s3:PutObject"],
      "Resource": "arn:aws:s3:::<example-data-lake-bucket>/*"
    },
    {
      "Effect": "Allow",
      "Action": "s3:ListBucket",
      "Resource": "arn:aws:s3:::<example-data-lake-bucket>",
      "Condition": {
        "StringEquals": {
          "aws:SourceVpce": "<your-vpc-endpoint-id>"
        }
      }
    },
    {
      "Effect": "Allow",
      "Action": ["glue:GetDatabase", "glue:GetTable"],
      "Resource": [
        "arn:aws:glue:us-east-1:<account-id>:catalog",
        "arn:aws:glue:us-east-1:<account-id>:database/streaming_db",
        "arn:aws:glue:us-east-1:<account-id>:table/streaming_db/*"
      ]
    },
    {
      "Effect": "Allow",
      "Action": ["kms:Decrypt", "kms:GenerateDataKey"],
      "Resource": "arn:aws:kms:us-east-1:<account-id>:key/<your-kms-key-id>"
    }
  ]
}

Scoping permissions to specific Amazon S3 buckets, AWS Glue databases, and AWS Key Management Service (AWS KMS) keys restrict access to only the resources your pipeline requires. Review IAM policies quarterly using the IAM Access Analyzer to identify and remove unused permissions.

Encryption — Configure server-side encryption with AWS Key Management Service (AWS KMS) customer managed keys (SSE-KMS) for your Amazon S3 buckets. Using customer managed keys requires additional review from your security team. Confirm your key management policies, rotation procedures, and access controls before implementation. Enable automatic key rotation annually. For encryption in transit, enforce TLS by adding a bucket policy that denies non-HTTPS access:

{
  "Effect": "Deny",
  "Principal": "*",
  "Action": ["s3:GetObject", "s3:PutObject", "s3:ListBucket"],
  "Resource": [
    "arn:aws:s3:::<example-data-lake-bucket>/*",
    "arn:aws:s3:::<example-data-lake-bucket>"
  ],
  "Condition": {
    "Bool": { "aws:SecureTransport": "false" }
  }
}

Amazon S3 bucket hardening — Enable Block Public Access on your buckets to prevent accidental public exposure:

aws s3api put-public-access-block \
  --bucket <example-data-lake-bucket> \
  --public-access-block-configuration \
  BlockPublicAcls=true,IgnorePublicAcls=true,BlockPublicPolicy=true,RestrictPublicBuckets=true

Enable versioning on buckets that store critical data and checkpoints to protect against accidental deletion. For production environments with sensitive data, consider enabling MFA Delete on versioned buckets. Enable S3 server access logging to track requests for security auditing.

Amazon Virtual Private Cloud (Amazon VPC) –Use Amazon VPC endpoints for private communication between your Apache Flink cluster and AWS services, removing public internet routing by keeping traffic within the AWS network.

Access logging – Enable AWS CloudTrail data events to log Amazon S3 object-level API calls (GetObject, PutObject) and Data Catalog API calls. Store logs in a separate Amazon S3 bucket with restricted access and enable log file integrity validation. Run regular compliance checks using AWS Config.

Operational practices

Set up a continuous integration and continuous deployment (CI/CD) pipeline to automate deployment and testing. Use version control to track schema and code changes. With Apache Iceberg’s schema evolution support, you can add columns without rewriting existing data files. Establish rollback procedures using Apache Iceberg’s snapshot-based architecture, so you can roll back to a previous table state if a bad write corrupts your data.

Troubleshooting

If you run into issues during setup or execution, use the following table to diagnose common errors.

Error Cause Solution
ClassNotFoundException Missing JAR files Check the dependencies in your lib directory and confirm HADOOP_CLASSPATH points to the correct path
Table not found Database name mismatch Check that the database name in t_env.use_database() matches the AWS Glue database where you registered your table
Checkpoint failures Amazon S3 permissions Check that your Amazon S3 bucket policy grants s3:PutObject for the checkpoint location
AWS credential errors Missing AWS IAM configuration Check that the AWS IAM role attached to your Apache Flink application has glue:GetTable, glue:GetDatabase, and s3:GetObject permissions on the relevant resources
Snapshot not found Table modified during query Increase monitor-interval or implement retry logic in your process_record() function
Schema mismatch Table schema changed between snapshots Review Apache Iceberg schema evolution settings and confirm backward compatibility

Clean up

To avoid ongoing charges, delete the resources that you created during this walkthrough.

  1. Stop your Amazon Managed Service for Apache Flink application. Open the Amazon Managed Service for Apache Flink console, choose your application name, choose Stop, and confirm the action. Or use the AWS CLI:

aws kinesisanalyticsv2 stop-application --application-name your-app-name

  1. Delete the Amazon S3 buckets that you created for data storage and checkpoints. For instructions, see Deleting a bucket in the Amazon S3 User Guide.
  2. Remove the Apache Iceberg tables from your Data Catalog.
  3. Delete the AWS IAM roles and policies created specifically for this walkthrough.
  4. If you created an Amazon VPC or Amazon VPC endpoints for testing, delete those resources.

Conclusion

Maintaining separate streaming and batch pipelines doubles your infrastructure costs, creates data synchronization issues, and adds operational complexity that slows your team down. In this post, you replaced that dual-pipeline architecture with a single system built on Apache Iceberg and Amazon Managed Service for Apache Flink. You configured a Flink environment with the required JAR dependencies, connected it to Data Catalog, and implemented streaming queries that read new records incrementally with exactly-once processing semantics. The same data, the same storage layer, the same schema—accessible to both your real-time and batch consumers.

To extend this solution, try these next steps based on your use case:

  • If you’re processing high volumes (>10,000 records/sec): Start with partition pruning. Add PARTITIONED BY (date_column) to your table definition, this typically reduces query times by 60–80%.
  • If you need production monitoring: Implement custom Amazon CloudWatch metrics. Track checkpoint duration, records processed per second, and backpressure to catch issues before they impact your pipeline.
  • If you have variable workloads: Configure auto scaling for your Apache Flink cluster. See the Amazon Managed Service for Apache Flink Developer Guide for detailed guidance.

Share your implementation experience in the comments, your use case, data volumes, latency improvements, and cost reductions help other readers calibrate their expectations. To get started, try the Amazon Managed Service for Apache Flink Developer Guide and the Apache Iceberg documentation on the Apache Iceberg website.


About the authors

Headshot of Nikhil

Nikhil Jha

Nikhil Jha is a Principal Delivery Consultant at AWS Professional Services, helping enterprises navigate complex modernization journeys. He builds data and AI solutions for AWS customers. Outside of work he likes swimming and hiking.

Headshot of Vyas

Vyas Garigipati

Vyas Garigipati is a Delivery Consultant at AWS Professional Services, with experience building scalable, distributed systems. He specializes in designing and building AI-powered, high-availability, multi-region architectures and helps customers deploy resilient, production ready solutions on AWS.

Headshot of Vafa

Vafa Ahmadiyeh

Vafa Ahmadiyeh is a Principal Lead Technologist at AWS, specializing in cloud architecture for the global financial services sector. He partners with major financial institutions to modernize their infrastructure and accelerate their migration to AWS, with a focus on building secure, scalable distributed systems and platforms designed for highly regulated environments.

Headshot of Kaushal

Kaushal (KK) Agrawal

Kaushal (KK) Agrawal is a Principal Technology Delivery Leader for the Digital Native Segment of AWS Professional Services, working with top-tier customers to deliver innovation at the intersection of AI and Cloud.

Build AWS Glue Data Quality pipeline using Terraform

Post Syndicated from Viquar Khan original https://aws.amazon.com/blogs/big-data/build-aws-glue-data-quality-pipeline-using-terraform/

AWS Glue Data Quality is a feature of AWS Glue that helps maintain trust in your data and support better decision-making and analytics across your organization. It allows users to define, monitor, and enforce data quality rules across their data lakes and data pipelines. With AWS Glue Data Quality, you can automatically detect anomalies, validate data against predefined rules, and generate quality scores for your datasets. This feature provides flexibility in how you validate your data – you can incorporate quality checks into your ETL processes for transformation-time validation, or validate data directly against cataloged tables for ongoing data lake monitoring. By leveraging machine learning, it can also suggest data quality rules based on your data patterns.
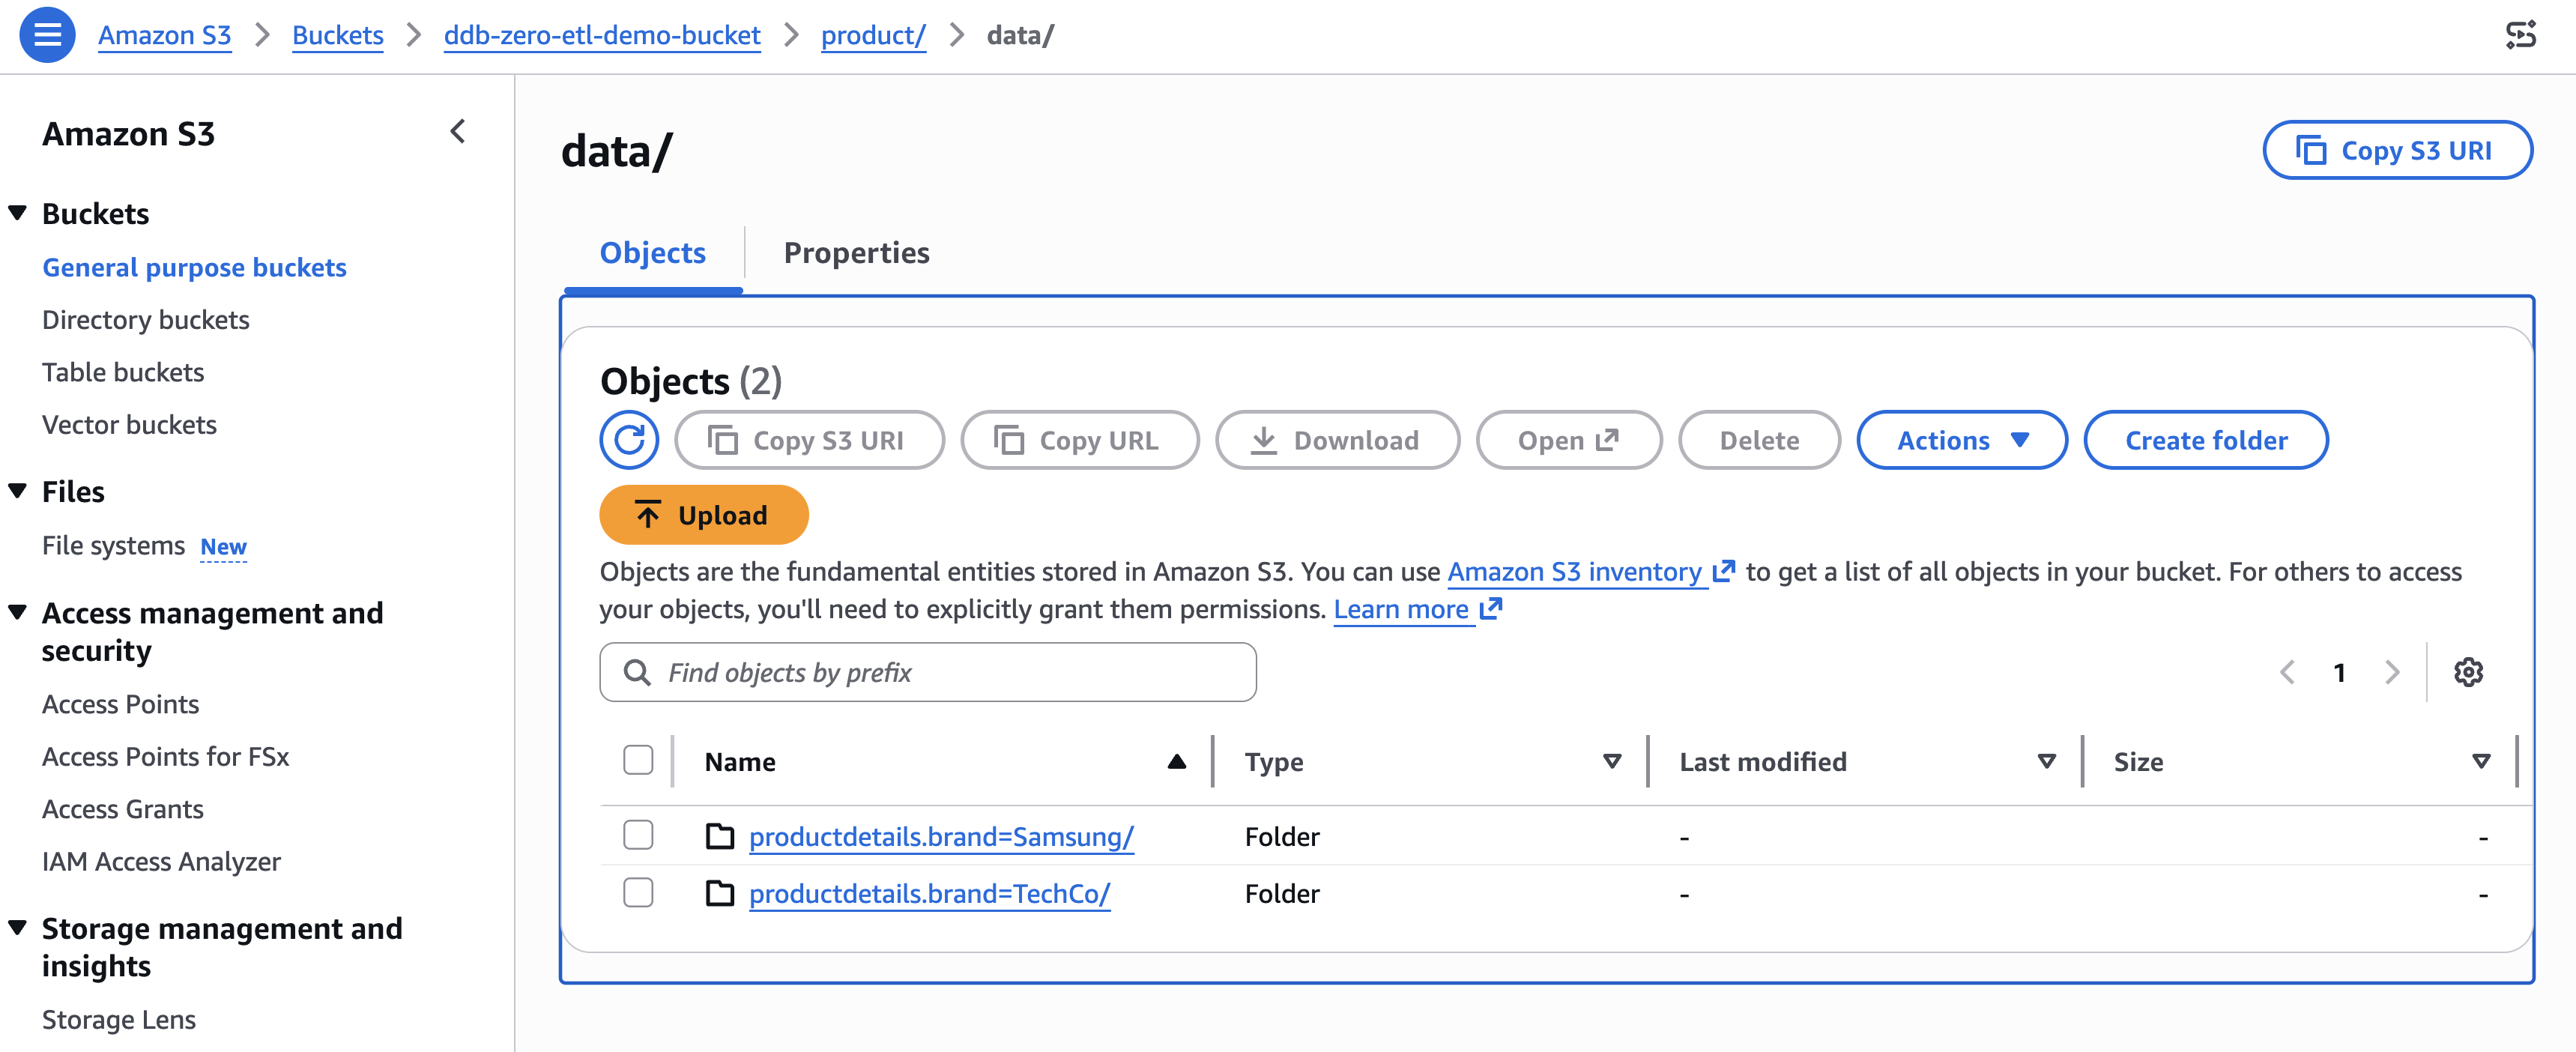
You can use Terraform, an open source Infrastructure as Code (IaC) tool developed by HashiCorp, to deploy AWS Glue Data Quality pipelines.

It allows developers and operations teams to define, provision, and manage cloud infrastructure using a declarative language. With Terraform, you can version, share, and reuse your infrastructure code across multiple cloud providers and services. Its powerful state management and planning capabilities enable teams to collaborate efficiently and maintain consistent infrastructure across different environments.

Using Terraform to deploy AWS Glue Data Quality pipeline enables IaC best practices to ensure consistent, version controlled and repeatable deployments across multiple environments, while fostering collaboration and reducing errors due to manual configuration.

In this post, we explore two complementary methods for implementing AWS Glue Data Quality using Terraform:

  1. ETL-based Data Quality – Validates data during ETL (Extract, Transform, Load) job execution, generating detailed quality metrics and row-level validation outputs
  2. Catalog-based Data Quality – Validates data directly against Glue Data Catalog tables without requiring ETL execution, ideal for monitoring data at rest

Solution overview

This post demonstrates how to implement AWS Glue Data Quality pipelines using Terraform using two complementary approaches mentioned above to ensure comprehensive data quality across your data lake.

We’ll use the NYC yellow taxi trip data, a real-world public dataset, to illustrate data quality validation and monitoring capabilities. The pipeline ingests parquet-formatted taxi trip data from Amazon Simple Storage Service (Amazon S3) and applies comprehensive data quality rules that validate data completeness, accuracy, and consistency across various trip attributes.

Method 1: ETL-based Data Quality

ETL-based Data Quality validates data during Extract, Transform, Load (ETL) job execution. This approach is ideal for:

  • Validating data as it moves through transformation pipelines
  • Applying quality checks during data processing workflows
  • Generating row-level validation outputs alongside transformed data

The pipeline generates two key outputs:

  • Data Quality Results – Detailed quality metrics and rule evaluation outcomes stored in the dqresults/ folder, providing insights into data quality trends and anomalies
  • Row-Level Validation – Individual records with their corresponding quality check results written to the processed/ folder, enabling granular analysis of data quality issues

Method 2: Catalog-based Data Quality

Catalog-based Data Quality validates data quality rules directly against AWS Glue Data Catalog tables without requiring ETL job execution. This approach is ideal for:

  • Validating data at rest in the data lake
  • Running scheduled data quality checks independent of ETL pipelines
  • Monitoring data quality across multiple tables in a database

Architecture overview

The following diagram illustrates how both approaches work together to provide comprehensive data quality validation:

  1. Source data stored in Amazon S3 (Yellow Taxi Data)
  2. AWS Glue ETL processes data with quality checks
  3. ETL validation results are stored in S3
  4. AWS Glue Crawler discovers schema
  5. Metadata is stored in AWS Glue Catalog
  6. AWS Glue Data Quality validates catalog tables
  7. Catalog validation results are stored in S3
  8. Amazon CloudWatch monitors all operations

By using AWS Glue’s serverless ETL capabilities and Terraform’s infrastructure-as-code approach, this solution provides a scalable, maintainable, and automated framework for ensuring data quality in your analytics pipeline.

Prerequisites:

Solution Implementation

Complete the following steps to build AWS Glue Data Quality pipeline using Terraform:

Clone the Repository

This post includes a GitHub repository that generates the following resources when deployed. To clone the repository, run the following command in your terminal:

git clone https://github.com/aws-samples/sample-build-aws-glue-data-quality-pipeline-using-terraform.git
cd sample-build-aws-glue-data-quality-pipeline-using-terraform

Core Infrastructure:

  • Amazon S3 bucket: glue-data-quality-{AWS AccountID}-{env} with AES256 encryption
  • Sample NYC taxi dataset (sample-data.parquet) automatically uploaded to the data/ folder
  • AWS Identity and Access Management (IAM) role: aws-glue-data-quality-role-{env} with Glue execution permissions and S3 read/write access
  • CloudWatch dashboard: glue-data-quality-{env} for monitoring job execution and data quality metrics
  • CloudWatch Log Groups for job logging with configurable retention

ETL-Based Data Quality Resources:

  • AWS Glue ETL job: data-quality-pipeline with 8 comprehensive validation rules
  • Python script: GlueDataQualityDynamicRules.py stored in glue-scripts/ folder
  • Results storage in dqresults/ folder with detailed rule outcomes
  • Row-level validation outputs in processed/ folder
  • Optional scheduled triggers for automated execution
  • CloudWatch alarm: etl-glue-data-quality-failure-{env} for monitoring job failures

Catalog-Based Data Quality Resources (Optional – when catalog_dq_enabled = true):

  • Glue Database: {catalog_database_name} for catalog table management
  • Glue Crawler: {job_name}-catalog-crawler for automatic schema discovery from S3 data
  • Crawler schedule trigger for automated execution (default: daily at 4 AM)
  • Glue Catalog Tables automatically discovered and created by the crawler
  • Catalog Data Quality job: {job_name}-catalog with 7 catalog-specific validation rules
  • Python script: CatalogDataQuality.py for catalog validation
  • Results storage in catalog-dq-results/ folder partitioned by table name
  • Catalog DQ schedule trigger for automated validation (default: daily at 6 AM)
  • CloudWatch alarm: catalog-glue-data-quality-failure-{env} for monitoring catalog job failures
  • Enhanced CloudWatch dashboard widgets for crawler status and catalog metrics

Review the Glue Data Quality Job Script

Review the Glue Data Quality job script GlueDataQualityDynamicRules.py located in the folder scripts, which has the following rules:

Rules = [
    CustomSql "select vendorid from primary where passenger_count > 0" with threshold > 0.9,
    Mean "trip_distance" < 150,
    Sum "total_amount" between 1000 and 100000,
    RowCount between 1000 and 1000000,
    Completeness "fare_amount" > 0.9,
    DistinctValuesCount "ratecodeid" between 3 and 10,
    DistinctValuesCount "pulocationid" > 100,
    ColumnCount = 19
]

Brief explanation of rules for NY Taxi data is as follows:

Rule Type Condition Description
CustomSql “select vendorid from primary where passenger_count > 0” with threshold > 0.9 Checks if at least 90% of rides have at least one passenger
Mean “trip_distance” < 150 Ensures the average trip distance is less than 150 miles
Sum “total_amount” between 1000 and 100000 Verifies that total revenue from all trips falls within this range
RowCount between 1000 and 1000000 Checks if the dataset has between 1,000 and 1 million records
Completeness “fare_amount” > 0.9 Ensures over 90% of records have a fare amount
DistinctValuesCount “ratecodeid” between 3 and 10 Verifies rate codes fall between 3-10 unique values
DistinctValuesCount “pulocationid” > 100 Checks if there are over 100 unique pickup locations
ColumnCount 19 Validates that dataset has exactly 19 columns

These rules together ensure data quality by validating volume, completeness, reasonable values and proper structure of the taxi trip data.

Configure Terraform Variables

Before deploying the infrastructure, configure your Terraform variables in the terraform.tfvars file located in the examples directory. This configuration determines which features will be deployed – ETL-based Data Quality only, or both ETL-based and Catalog-based Data Quality.

Basic Configuration

The solution uses default values for most settings, but you can customize the following in your terraform.tfvars file:

  • AWS Region – The AWS region where resources will be deployed
  • Environment – Environment identifier (such as, “dev”, “prod”) used in resource naming
  • Job Name – Name for the Glue job (default: data-quality-pipeline)

Enable Catalog-Based Data Quality

By default, the solution deploys only ETL-based Data Quality. To enable Catalog-based Data Quality validation, add the following configuration to your terraform.tfvars file:

# Enable Catalog-based Data Quality
catalog_dq_enabled = true

# Glue Database name for catalog tables
catalog_database_name = "taxi_data_catalog"

# S3 paths containing parquet data for catalog table creation
s3_data_paths = ["data/"]

# Optional: Specific table names to validate (empty = all tables in database)
catalog_table_names = []

# Data quality rules for catalog validation
catalog_dq_rules = <<EOF
Rules = [
  RowCount > 0,
  Completeness "vendorid" > 0.9,
  Completeness "passenger_count" > 0.95,
  Mean "trip_distance" < 150,
  ColumnCount > 5
]
EOF

# Enable scheduled execution for catalog data quality
catalog_enable_schedule = false
catalog_schedule_expression = "cron(0 6 * * ? *)"

# Crawler schedule for automatic table discovery
catalog_crawler_schedule = "cron(0 4 * * ? *)"

Configuration Notes:

  • catalog_dq_enabled – Set to true to enable Catalog-based validation alongside ETL-based validation,which will deploy both ETL and Catalog validation
  • catalog_database_name – Name of the Glue database that will be created for catalog tables
  • s3_data_paths – S3 folders containing parquet data that the Glue Crawler will discover
  • catalog_table_names – Leave empty to validate all tables, or specify specific table names
  • catalog_dq_rules – Define validation rules specific to catalog tables (can differ from ETL rules)
  • catalog_enable_schedule – Set to true to enable automatic scheduled execution
  • Schedule expressions – Use cron format for automated execution (crawler runs before DQ job)

Once you’ve configured your variables, save the terraform.tfvars file and proceed to the next step.

Set Up AWS CLI Authentication

Before you can interact with AWS services using the command line, you need to set up and authenticate the AWS CLI. This section guides you through the process of configuring your AWS CLI and verifying your authentication. Follow these steps to ensure you have the necessary permissions to access AWS resources.

  1. Open your terminal or command prompt.
  2. Set up authentication in the AWS CLI. You need administrator permissions to set up this environment.
    aws configure

  3. To test if your AWS CLI is working and you’re authenticated, run the following command:
    aws sts get-caller-identity --output json

    The output should look similar to the following:

    {
       "UserId": "UUID123123:your_user",
      "Account": "111122223333",
    "Arn": "arn:aws:sts::111122223333:assumed-role/some-role/your_user"
     }

Deploy with Terraform

Follow these steps to deploy your infrastructure using Terraform. This process will initialize your working directory, review planned changes, and apply your infrastructure configuration to AWS.

To deploy with Terraform, navigate to the examples folder by running the following command in your CLI from inside the repository

cd .\examples

Run the following bash commands:

terraform init
 

Initializes a Terraform working directory, downloads required provider plugins, and sets up the backend for storing state.

On success you will receive output Terraform has been successfully initialized!

terraform plan
 

Creates an execution plan, shows what changes Terraform will make to your infrastructure. This command doesn’t make any changes.

terraform apply
 

Deploys infrastructure and code to the AWS Account. By default, it asks for confirmation before making any changes. Use ‘terraform apply -auto-approve’ to skip the confirmation step.

When prompted with ‘Do you want to perform these actions?’, type ‘yes’ and press Enter to confirm and allow Terraform to execute the described actions.

Upon successful execution, the system will display ‘Apply complete!’ message.

Run the AWS Glue Data Quality Pipeline

After deploying the infrastructure with Terraform, you can validate data quality using two methods – ETL-based and Catalog-based. Each method serves different use cases and can be run independently or together.

Method 1: Run the ETL-Based Data Quality Job

ETL-based data quality validates data during the transformation process, making it ideal for catching issues early in your data pipeline.

Steps to execute:

  1. Navigate to the AWS Glue Console and select ETL Jobs from the left navigation panel
  2. Locate and select the job named data-quality-pipeline
  3. Choose Run to start the job execution
  4. Monitor the job status – it typically completes in 2-3 minutes
  5. Review the results:
    • Once completed, click on the Data Quality tab to review the validation results.

      The following screenshot shows the results.

    • Understanding AWS Glue Data Quality Results: NYC Taxi Data Example.

      Rule Results Summary

      • We had 8 total rules
      • 7 rules passed
      • 1 rule failed
      Rule Rule Condition Status Pass/Fail Reason
      Passenger Count Check At least 90% of rides should have at least one passenger Passed 95% of rides had passengers, exceeding 90% threshold
      Trip Distance Average trip < 150 miles Passed Average was 5.94 miles, well below 150-mile limit
      Row Count Between 1,000 and 1,000,000 records Passed 63,441 records fell within required range
      Fare Amount Completeness 90% of records should have fare amounts Passed 100% completeness exceeded 90% requirement
      Rate Code Variety Between 3-10 different rate codes Passed 7 unique codes fell within acceptable range
      Pickup Locations More than 100 different pickup locations Passed 205 locations exceeded minimum requirement
      Column Count Exactly 19 columns Passed Exact match at 19 columns
      Total Amount Range Sum of all fares between $1,000 and $100,000 Failed Total of $130,638.29 exceeded maximum limit
    • Check the S3 bucket for detailed outputs:
      • Data Quality metrics: s3://glue-data-quality-{AccountID}-{env}/dqresults/
      • Row-level validation: s3://glue-data-quality-{AccountID}-{env}/processed/

The job processes the NYC taxi data and applies all 8 validation rules during the ETL execution. You’ll see a quality score along with detailed metrics for each rule.

Method 2: Run the Catalog-Based Data Quality Pipeline

Catalog-based data quality validates data at rest in your data lake, independent of ETL processing. This method requires the Glue Crawler to first discover and catalog your data.

  1. Run the Glue Crawler (first-time setup or when schema changes):
    • Navigate to AWS Glue Console and select Crawlers
    • Locate data-quality-pipeline-catalog-crawler
    • Select data-quality-pipeline-catalog-crawler checkbox and click Run and wait for completion (1-2 minutes)
    • Verify the table was created in your Glue database
  2. Run the Catalog Data Quality Job:
    • Navigate to the AWS Glue Console and select ETL Jobs from the left navigation panel
    • Select the job named data-quality-pipeline-catalog
    • Click Run job to execute the validation
    • Monitor the job status until completion

  3. Review the results:
    • Once completed, click on the Data Quality tab to review the validation results.

      The following screenshot shows the results.

      Rule Results Summary

      • We had 7 total rules
      • 6 rules passed
      • 1 rule failed
      Rule Rule Condition Status Pass/Fail Reason
      Row Count Row count should be greater than zero Passed 63441 rows present in the source data file
      Completeness “vendorid” 90% of records should have vendorid Passed 100% completeness exceeded 90% requirement
      Completeness “passenger_count” 95% of records should have vendorid Passed 96% completeness exceeded 95% requirement
      Mean “trip_distance” Mean “trip_distance” < 150 Passed trip_distance.Mean: 5.94 which is less than threshold 150
      Sum “total_amount” Sum “total_amount” between 1000 and 100000 Failed total_amount.Sum: 1330638.29 which does not satisfy condition
      Distinct vale count “ratecodeid” DistinctValuesCount “ratecodeid” between 3 and 10 Passed ratecodeid.DistinctValuesCount: 7, satisfies condition
      Column Count Greater than 5 columns Passed ColumnCount: 19, satisfies condition
    • Check the S3 bucket for detailed outputs s3://glue-data-quality-{AccountID}-{env}/catalog-dq-results/

Catalog vs ETL Data Quality Comparison

Feature ETL Data Quality Catalog Data Quality
Execution Context Validates data during ETL job processing Validates data against catalog tables at rest
Data Source Reads directly from S3 files (parquet format) Queries Glue Data Catalog tables
Results Location s3://…/dqresults/ s3://…/catalog-dq-results/
Primary Use Case Validate data quality during transformation pipelines Monitor data lake quality independent of ETL workflows
Execution Trigger Runs as part of Glue ETL job execution Runs independently as scheduled Data Quality job
Scheduling Configured via Glue job schedule or on-demand Configured via Data Quality job schedule or on-demand
Table Discovery Manual – requires explicit S3 path configuration Automatic – Glue Crawler discovers schema and creates tables
Schema Management Defined in ETL job script Managed by Glue Data Catalog
Output Format Data Quality metrics + row-level validation outputs Data Quality metrics only
Best For Catching issues early in data pipelines Ongoing monitoring of data at rest in data lakes
Dependencies Requires ETL job execution Requires Glue Crawler to run first
CloudWatch Integration Job-level metrics and logs Data Quality-specific metrics and logs

Monitoring and Troubleshooting

Both data quality methods automatically send metrics and logs to Amazon CloudWatch. You can set up alarms to notify you when quality scores drop below acceptable thresholds.

Clean up

To avoid incurring unnecessary AWS charges, make sure to delete all resources created during this tutorial. Ensure you have backed up any important data before running these commands, as this will permanently delete the resources and their associated data. To destroy all resources created as part of this blog, run following command in your terminal:

terraform destroy

Conclusion

In this blog post, we demonstrated how to build and deploy a scalable data quality pipeline using AWS Glue Data Quality and Terraform. The solution implements two validation methods:

  1. ETL-based Data Quality – Integrated validation during ETL job execution for transformation pipeline quality assurance
  2. Catalog-based Data Quality – Independent validation against Glue Data Catalog tables for data lake quality monitoring

By implementing data quality checks on NYC taxi trip data, we showed how organizations can automate their data validation processes and maintain data integrity at scale. The combination of AWS Glue’s serverless architecture and Terraform’s infrastructure-as-code capabilities provides a powerful framework for implementing reproducible, version-controlled data quality solutions. This approach not only helps teams catch data issues early but also enables them to maintain consistent data quality standards across different environments. Whether you’re dealing with small datasets or processing massive amounts of data, this solution can be adapted to meet your organization’s specific data quality requirements. As data quality continues to be a crucial aspect of successful data initiatives, implementing automated quality checks using AWS Glue Data Quality and Terraform sets a strong foundation for reliable data analytics and decision-making.

To learn more about AWS Glue Data Quality, refer to the following:


About the authors

Viquar Khan

Viquar Khan

Viquar is a Senior Data Architect at AWS who transforms complex data challenges into scalable, production-ready solutions. With 22+ years of expertise spanning data engineering, AI/ML, and Generative AI, he is a published author, open-source contributor, and passionate about pushing the boundaries of what’s possible with data.

Mahammadali Saheb

Mahammadali Saheb

Mahammadali is a Sr. Data Architect at AWS Professional Services, specializing in Data Analytics. He is passionate about helping customers drive business outcome via data analytics solutions on AWS Cloud.

Extract data from Amazon Aurora MySQL to Amazon S3 Tables in Apache Iceberg format

Post Syndicated from Kunal Ghosh original https://aws.amazon.com/blogs/big-data/extract-data-from-amazon-aurora-mysql-to-amazon-s3-tables-in-apache-iceberg-format/

If you manage data in Amazon Aurora MySQL-Compatible Edition and want to make it available for analytics, machine learning (ML), or cross-service querying in a modern lakehouse format, you’re not alone.

Organizations often need to run analytics, build ML models, or join data across multiple sources. These are examples of workloads that can be resource-intensive and impractical to run directly against a transactional database. By extracting your Aurora MySQL data into Amazon S3 Tables in Apache Iceberg format, you can offload analytical queries from your production database without impacting its performance, while storing data in a fully managed Iceberg table store optimized for analytics. Built on the open Apache Iceberg standard, Amazon Simple Storage Service (Amazon S3) Table data is queryable from engines like Amazon Athena, Amazon Redshift Spectrum, and Apache Spark without additional data copies. You can also combine relational data with other datasets already in your data lake, enabling richer cross-domain insights.

Apache Iceberg and Amazon S3 Tables

Apache Iceberg is a widely adopted open table format that offers Atomicity, Consistency, Isolation, Durability (ACID) transactions, schema evolution, and time travel capabilities. It enables multiple engines to work concurrently on the same dataset, making it a popular choice for building open lakehouse architectures.

Amazon S3 Tables is a purpose-built, fully managed Apache Iceberg table store designed for analytics workloads. It delivers up to 3x faster query performance and up to 10x more transactions per second compared to self-managed Iceberg tables. It also automatically compacts data and removes unreferenced files to optimize storage and performance.

In this post, you learn how to set up an automated, end-to-end solution that extracts tables from Amazon Aurora MySQL Serverless v2 and writes them to Amazon S3 Tables in Apache Iceberg format using AWS Glue. The entire infrastructure is deployed using a single AWS CloudFormation stack.

Requirements

AWS offers zero-ETL integrations from Amazon Aurora to Amazon Redshift and Amazon SageMaker AI, enabling seamless data flow for analytics and machine learning workloads.

However, there isn’t yet a native zero-ETL integration between Amazon Aurora and Amazon S3 Tables. This means that organizations looking to use Amazon S3 Tables for their Lakehouse architecture currently face several requirements:

  • Setting up ETL pipelines to extract data from Amazon Aurora and transform it into Apache Iceberg format
  • Configuring networking and security for AWS Glue jobs to access Amazon Aurora databases in private subnets
  • Coordinating the provisioning of source databases, ETL pipelines, and target table stores
  • Managing the end-to-end workflow without native automation

Solution overview

In this solution, you automate the extraction of relational database tables from Amazon Aurora MySQL Serverless v2 to Amazon S3 Tables in Apache Iceberg format using AWS Glue 5.0. To help you get started and test this solution, a CloudFormation template is provided. This template provisions the required infrastructure, loads sample data, and configures the Extract, Transform, Load (ETL) pipeline. You can adapt this template for your own scenario.

Solution overview

Sample data

This solution uses the TICKIT sample database, a well-known dataset used in Amazon Redshift documentation. The TICKIT data models a fictional ticket sales system with seven interrelated tables: users, venue, category, date, event, listing, and sales. The dataset is publicly available as mentioned in the Amazon Redshift Getting Started Guide.

Solution flow

The solution flow as shown in the previous architecture diagram:

  1. An AWS Lambda function downloads the TICKIT sample dataset (a fictional ticket sales system used in Amazon Redshift documentation) from a public Amazon S3 bucket to a staging S3 bucket.
  2. A second Lambda function, using PyMySQL (a Python MySQL client library), loads the staged data files into the Aurora MySQL Serverless v2 database using LOAD DATA LOCAL INFILE.
  3. The AWS Glue job reads seven TICKIT tables from Aurora MySQL through a native MySQL connection and writes them to Amazon S3 Tables in Apache Iceberg format using the S3 Tables REST catalog endpoint with SigV4 authentication.
  4. You can query the migrated data in S3 Tables using Amazon Athena.

The solution consists of the following key components:

  1. Amazon Aurora MySQL Serverless v2 as the source relational database containing the TICKIT sample dataset (users, venue, category, date, event, listing, and sales tables)
  2. AWS Secrets Manager to store the Aurora MySQL database credentials securely
  3. Amazon S3 staging bucket for the TICKIT sample data files downloaded from the public redshift-downloads S3 bucket
  4. AWS Lambda functions using PyMySQL to load data into Aurora MySQL
  5. AWS Glue 5.0 job (PySpark) to read tables from Aurora MySQL and write them to S3 Tables in Apache Iceberg format
  6. Amazon S3 Tables as the target storage for the migrated Iceberg tables
  7. Amazon VPC with private subnets and VPC endpoints for Amazon S3, S3 Tables, AWS Glue, Secrets Manager, AWS Security Token Service (AWS STS), CloudWatch Logs, and CloudFormation

Here are some advantages of this architecture:

  • Fully automated setup: A single CloudFormation stack provisions the required infrastructure, loads sample data, and configures the ETL pipeline.
  • Serverless and cost-efficient: Aurora MySQL Serverless v2 and AWS Glue both scale based on demand, minimizing idle costs.
  • Apache Iceberg table format: Data is stored in Apache Iceberg format, enabling ACID transactions, schema evolution, and time travel queries.
  • Network isolation and credential management: The resources run within private subnets with Virtual Private Cloud (VPC) endpoints, and database credentials are managed through AWS Secrets Manager.
  • Extensible pattern: The same approach can be adapted for other relational databases (PostgreSQL, SQL Server) and other target formats supported by AWS Glue.

Prerequisites

To follow along, you need an AWS account. If you don’t yet have an AWS account, you must create one. The CloudFormation stack deployment takes approximately 30-45 minutes to complete and requires familiarity with Amazon S3 Tables, AWS CloudFormation, Apache Iceberg, AWS Glue, Amazon Aurora. This solution will incur AWS costs. The main cost drivers are AWS Glue ETL job runs (billed per DPU-hour, proportional to data volume) and Amazon S3 Tables storage and request charges. Remember to clean up resources when you are done to avoid unnecessary charges.

CloudFormation parameters

You can configure the following parameters before deploying the CloudFormation stack:

Parameter Description Default Required
S3TableBucketName Name of the S3 Tables bucket to create (or use existing) Yes
DatabaseName Name of the initial Aurora MySQL database tickit No
MasterUsername Master username for Aurora MySQL admin No
VpcCidr CIDR block for the VPC 10.1.0.0/16 No
S3TableNamespace Namespace for S3 Tables tickit No

Implementation walkthrough

The following steps walk you through the implementation. These steps are to deploy and test an end-to-end solution from scratch. If you are already running some of these components, you may skip to the relevant step. You can also refer to the aws-samples repository, sample-to-write-aurora-mysql-to-s3tables-using-glue for the entire solution.

Step 1: Deploy the CloudFormation stack

Deploy the CloudFormation template scripts/aurora-mysql-to-s3tables-stack.yaml using the AWS Console or the AWS Command Line Interface (AWS CLI). Provide a name for the S3 Tables bucket; the stack will create it automatically (or use an existing one if it already exists).

To deploy using the AWS Console (recommended), navigate to the AWS CloudFormation Console and use the CloudFormation template. Alternatively, to deploy using the AWS CLI first upload the template to an S3 bucket (the template exceeds the 51,200 byte limit for inline –template-body), then create the stack.

# Upload the template to S3
aws s3 cp scripts/aurora-mysql-to-s3tables-stack.yaml \
  s3://<your-s3-bucket>/aurora-mysql-to-s3tables-stack.yaml \
  --region <your-region>
# Create the stack using the S3 template URL
aws cloudformation create-stack \
  --stack-name aurora-mysql-tickit-stack \
  --template-url https://<your-s3-bucket>.s3.<your-region>.amazonaws.com/aurora-mysql-to-s3tables-stack.yaml \
  --parameters \
    ParameterKey=S3TableBucketName,ParameterValue=<your-s3-table-bucket-name> \
  --capabilities CAPABILITY_NAMED_IAM \
  --region <your-region>

The stack will automatically:

  • Create the S3 Tables bucket (or use existing if it already exists)
  • Create a VPC with private subnets and VPC endpoints
  • Provision an Aurora MySQL Serverless v2 cluster
  • Download TICKIT sample data from the public Amazon S3 bucket
  • Load the sample data into Aurora MySQL via a Lambda function using PyMySQL
  • Create a Glue job configured to migrate data to S3 Tables in Iceberg format

Note: The S3 Tables bucket is retained when the stack is deleted to preserve your data.

Step 2: Verify the Aurora MySQL data

Retrieve the AuroraClusterEndpoint, DatabaseName, and SecretArn values from the CloudFormation stack, make a note of the AuroraClusterEndpoint, DatabaseName, and SecretArn. You can navigate to the Amazon Aurora Console, choose the Query Editor, and enter the values from the CloudFormation stack to connect. You can also choose your preferred method of connecting to an Amazon Aurora DB cluster.

Use the AWS CLI to retrieve the stack outputs: –

aws cloudformation describe-stacks --stack-name aurora-mysql-tickit-stack --region <your-region> --query "Stacks[0].Outputs"

Then run the following SQL commands to verify the data load:

-- Verify if the tables are created
SELECT * FROM information_schema.tables WHERE table_schema = 'tickit';

-- Verify if the data is loaded
SELECT 'users' AS table_name, COUNT(*) AS record_count FROM tickit.users
UNION ALL SELECT 'venue', COUNT(*) FROM tickit.venue
UNION ALL SELECT 'category', COUNT(*) FROM tickit.category
UNION ALL SELECT 'date', COUNT(*) FROM tickit.date
UNION ALL SELECT 'event', COUNT(*) FROM tickit.event
UNION ALL SELECT 'listing', COUNT(*) FROM tickit.listing
UNION ALL SELECT 'sales', COUNT(*) FROM tickit.sales;

Step 3: Run the Glue job

Navigate to the AWS Glue Console, choose ETL jobs under Data Integration and ETL from the left panel. Select the AWS Glue job mysql-tickit-to-iceberg-job and choose Run job to start execution. You can also start the ETL job using the AWS CLI:

aws glue start-job-run --job-name mysql-tickit-to-iceberg-job --region <your-region>

The AWS Glue job performs the following operations for each of the seven TICKIT tables:

  • Reads the table from Aurora MySQL through the native MYSQL Glue connection
  • Converts the data to a Spark DataFrame
  • Creates the Iceberg table in the S3 Tables namespace using CREATE TABLE IF NOT EXISTS with the USING ICEBERG clause
  • Inserts the data using INSERT INTO (or INSERT OVERWRITE if the table already exists)
  • Verifies the record count and displays sample data

Step 4: Verify the results

After the AWS Glue job completes, verify that the tables have been created in your S3 Table bucket by navigating to the Amazon S3 Console. Choose Table buckets under Buckets and select your S3 Table bucket. You can also verify using the AWS CLI:

aws s3tables list-tables \
  --table-bucket-arn arn:aws:s3tables:<your-region>:<your-account-id>:bucket/<your-s3-table-bucket-name> \
  --namespace tickit \
  --region <your-region>

Select a table from the tickit namespace and choose Preview to inspect the data.

Preview S3 data

You can also query the migrated tables using Amazon Athena to validate the data.

Clean up resources

Remember to clean up resources when you no longer need them to avoid unnecessary charges.

Navigate to the CloudFormation console, search for your stack and choose Delete. Alternatively, use the AWS CLI:

aws cloudformation delete-stack --stack-name aurora-mysql-tickit-stack --region <your-region>

The S3 Tables bucket is retained by default. To delete it, use the Amazon S3 console or the AWS CLI to remove the table bucket separately. The staging S3 bucket will be automatically emptied and deleted as part of the stack deletion.

aws s3tables delete-table-bucket --table-bucket-arn arn:aws:s3tables:<your-region>:<your-account-id>:bucket/<your-s3-table-bucket-name> --region <your-region>

Summary

In this post, we showed you how to extract data from Amazon Aurora MySQL Serverless v2 and write it to Amazon S3 Tables in Apache Iceberg format using AWS Glue 5.0. By using the native Iceberg support of AWS Glue and the S3 Tables REST catalog endpoint, you can bridge the gap between relational databases and modern lakehouse storage formats. By automating the entire pipeline through CloudFormation, you can quickly set up and replicate this pattern across multiple environments.

As AWS Glue and Amazon S3 Tables continue to evolve, you can take advantage of future enhancements while maintaining this automated migration pattern.

If you have questions or suggestions, leave us a comment.


About the authors

Kunal Ghosh

Kunal Ghosh

Kunal is a Sr. Solutions Architect at AWS. He is passionate about building efficient and effective solutions on AWS, especially involving generative AI, analytics, data science, and machine learning. Besides family time, he likes reading, swimming, biking, and watching movies.

Arghya Banerjee

Arghya Banerjee

Arghya is a Sr. Solutions Architect at AWS in the San Francisco Bay Area, focused on helping customers adopt and use the AWS Cloud. He is focused on big data, data lakes, streaming and batch analytics services, and generative AI technologies.

Indranil Banerjee

Indranil Banerjee

Indranil is a Sr. Solutions Architect at AWS in the San Francisco Bay Area, focused on helping customers in the hi-tech and semi-conductor sectors solve complex business problems using the AWS Cloud. His special interests are in the areas of legacy modernization and migration, building analytics platforms and helping customers adopt cutting edge technologies such as generative AI.

Vipan Kumar

Vipan Kumar

Vipan is a Sr. Solutions Architect at AWS, where he works with strategic customers. He has extensive experience in machine learning and generative AI. With a background in application development, he is passionate about designing and building enterprise applications for the cloud.

Implement a data mesh pattern in Amazon SageMaker Catalog without changing applications

Post Syndicated from Paolo Romagnoli original https://aws.amazon.com/blogs/big-data/implement-a-data-mesh-pattern-with-amazon-sagemaker-catalog-without-making-changes-to-your-applications/

When creating a project in Amazon SageMaker Unified Studio, users select a project profile to define resources and tools to be provisioned in the project. These are used by Amazon SageMaker Catalog to implement a data mesh pattern. Some users don’t want to take advantage of resources provisioned along with the project for various reasons. For instance, they may want to avoid making changes to their existing applications and data products.

This post shows you how to implement a data mesh pattern by using Amazon SageMaker Catalog while keeping your current data repositories and consumer applications unchanged.

Solution overview

In this post, you will simulate a scenario based on data producer and data consumer that exists before Amazon SageMaker Catalog adoption. For this purpose, you will use a sample dataset to simulate existing data and simulate an existing application using an AWS Lambda function. You can apply the same solution to your real-life data and workloads.

The following diagram illustrates the solution architecture’s key configurations. In this architecture, the Amazon Simple Storage Service (Amazon S3) bucket and the AWS Glue Data Catalog in the producer account simulate the existing data repository. The Lambda function in the consumer account simulates the existing consumer application.

AWS cross-account data sharing via SageMaker & Lake Formation: Producer publishes to catalog, Consumer subscribes & accesses data

Here is a description of the key configurations highlighted in the architecture:

  1. As part of an Amazon SageMaker domain, create a producer project (associated to a producer account) and a consumer project (associated to a consumer account). Among other resources, a project AWS Identity and Access Management (IAM) role is created for each project in the associated account.
  2. In the producer account, use AWS Lake Formation to grant producer project’s IAM role permissions to access the existing data asset.
  3. Publish the data asset in the Amazon SageMaker Catalog from the producer project.
  4. Subscribe the data asset from the consumer project.
  5. In the consumer account, configure your Lambda function to assume consumer project’s IAM role to access the subscribed data asset.

The solution architecture is based on the following Amazon Web Services (AWS) services and features:

  • Amazon SageMaker Catalog offers you a way to discover, govern, and collaborate on data and AI securely.
  • Amazon SageMaker Unified Studio provides a single data and AI development environment to discover and build with your data. Amazon SageMaker Unified Studio projects provide collaborative boundaries for users to accomplish data and AI tasks.
  • The lakehouse architecture of Amazon SageMaker is fully compatible with Apache Iceberg. It unifies data across Amazon S3 data lakes, Amazon Redshift data warehouses, and third-party and federated data sources.
  • AWS Lake Formation, which you can use centrally to govern, secure, and share data for analytics and machine learning.
  • AWS Glue Data Catalog is a persistent metadata store for your data assets. It contains table definitions, job definitions, schemas, and other control information to help you manage your AWS Glue environment.
  • Amazon S3 is an object storage service that offers industry-leading scalability, data availability, security, and performance.

Setting up resources

In this section, you will prepare the resources and configurations you need for this solution.

Three AWS accounts

To follow this solution, you need three AWS accounts, and it’s better if they’re part of the same organization in AWS Organizations:

  • Producer account – Hosts the data asset to be published
  • Consumer account – Hosts the application that consumes the data published from the producer account
  • Governance account – Where the Amazon SageMaker Unified Studio domain is configured

Each account must have an Amazon Virtual Private Cloud (Amazon VPC) with at least two private subnets in two different Availability Zones. For instruction, refer to Create a VPC plus other VPC resources. Make sure to create both VPCs in the same Region you plan to apply this solution.

A governance account is used for the sake of convenience, but it’s not strictly needed because Amazon SageMaker can be configured and managed in producer or consumer accounts.If you don’t have access to three accounts, you can still use this post to understand the key configurations required to implement a data mesh pattern with Amazon SageMaker Catalog while keeping your current data repositories and consumer applications unchanged.

Create a data repository in the producer account

First, create a sample dataset by following these instructions:

  1. Open a text editor.
  2. Paste the following text in a new file:
    name,stars
    	oak,3
    	maple,2
    	birch,3
    	willow,4
    	pine,5
    	mango,1
    	neem,2
    	banyan,5
    	eucalyptus,3
    	teak,2

  3. Save the file as trees.csv. This is your sample data file.

After you create the sample dataset, create an S3 bucket and an AWS Glue database in the producer account, which will act as the data repository.

Create the S3 bucket and upload the trees.csv file in the producer account:

  1. Access the S3 console in the producer account.
  2. Create an S3 bucket. For instructions, refer to Creating a general purpose bucket.
  3. Upload to the S3 bucket the trees.csv sample data file that you created. For instructions, refer to Uploading objects.

Create the AWS Glue database and table in the producer account:

  1. Access the Glue console in the producer account.
  2. In the navigation pane, under Data Catalog, choose Databases.
  3. Choose Add database.
  4. For Name, enter collections.
  5. For Description, enter This database contains collections of statistics for natural resources.
  6. Choose Create database.
  7. In the navigation pane, under Data Catalog, choose Tables.
  8. Choose Add table.
  9. In the table creation guided procedure, enter the following input for Step 1: Set table properties:
    1. For Name, enter trees.
    2. For Database, select collections.
    3. For Description, enter This table captures ratings data related to the characteristics of various tree species.
    4. For Table format, select Standard AWS Glue table (default).
    5. For Select the type of source, select S3.
    6. For Data location is specified in, select my account.
    7. For Include path, enter s3://<bucket-name>/<prefix>/ where <bucket-name> is the name of the S3 bucket you created earlier in this procedure and <prefix> is the optional prefix for the trees.csv file you uploaded.
    8. For Data format, select CSV.
    9. For Delimeter, select Comma (,).
  10. Choose Next.
  11. For Step 2: Choose or define schema, enter the following:
    1. For Schema, select Define or upload a schema.
    2. Choose Edit schema as JSON and enter the following schema in the pop-up:
      [
        {
          "Name": "name",
          "Type": "string",
          "Parameters": {}
        },
        {
          "Name": "stars",
          "Type": "string",
          "Parameters": {}
        }
      ]

    3. Choose Save.
    4. Choose Next.
    5. Choose Create.

Create a Lambda function in the consumer account

Create the Lambda function in the consumer account. This will simulate a data consumer application.First, in the consumer account create the IAM policy and the IAM role to be assigned to the Lambda function:

  1. Access the IAM console in the consumer account.
  2. Create an IAM policy and name it smus_consumer_athena_execution by using the following policy. Make sure to replace placeholders <AWS_Region> and <AWS_account_ID_number> with your Region and consumer account ID number. You will replace the <workgroup_id> placeholder later. For IAM policy creation instructions, refer to Create IAM policies (console).
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "AthenaExecution",
                "Action": [
                    "athena:StartQueryExecution",
                    "athena:GetQueryExecution",
                    "athena:GetQueryResults"
                ],
                "Effect": "Allow",
                "Resource": "arn:aws:athena:<AWS_Region>:<AWS_account_ID_number>:workgroup/<workgroup_id>"
            }
        ]
    }

  3. Create an IAM role for AWS Lambda service and name it smus_consumer_lambda. Assign to it the AWS managed permission AWSLambdaBasicExecutionRole and the permission named smus_consumer_athena_execution that you just created. For instructions, refer to Create a role to delegate permissions to an AWS service.

After the IAM role for the Lambda function is in place, you can create the Lambda function in the consumer account:

  1. Access the Lambda console in the consumer account.
  2. In the navigation pane, choose Functions.
  3. Choose Create function and enter the following information:
    1. For Function name, enter consumer_function.
    2. For Runtime, select Python 3.14.
    3. Expand Change default execution role section.
    4. For Execution role, select Use an existing role.
    5. For Existing role, select smus_consumer_lambda.
  4. Choose Create function.
  5. Under the Code tab, in the Code source, replace the existing code with the following:
    import boto3
    import time
    sts_client = boto3.client('sts')
    role_arn = "<role_arn>"
    session_name = "AthenaQuerySession"
    catalog = "AwsDataCatalog"
    database = "<database_name>"
    workgroup = "<workgroup_id>"
    query = "select * from "+catalog+"."+database+".trees"
    def lambda_handler(event, context):
        # Assume SageMaker Unified Studio project role
        assumed_role_object = sts_client.assume_role(
            RoleArn=role_arn,
            RoleSessionName=session_name
        )
        # Get temporary credentials
        credentials = assumed_role_object['Credentials']
        # Create Athena client using temporary credentials
        athena = boto3.client(
            'athena',
            aws_access_key_id=credentials['AccessKeyId'],
            aws_secret_access_key=credentials['SecretAccessKey'],
            aws_session_token=credentials['SessionToken'],
            region_name='eu-west-1'
        )
        # Execute Athena Query
        response = athena.start_query_execution(
            QueryString=query,
            QueryExecutionContext={
                'Database': database,
                'Catalog': catalog
            },
            WorkGroup=workgroup
        )
        query_execution_id = response['QueryExecutionId']
        # Polling with exponential backoff
        wait_time = 0.25  # Start with 0.25 seconds
        max_wait = 8      # Maximum wait time of 8 seconds
        
        while True:
            result = athena.get_query_execution(QueryExecutionId=query_execution_id)
            state = result['QueryExecution']['Status']['State']
            if state in ['FAILED', 'CANCELLED']:
                raise Exception(f"Query {state}")
            elif state == 'SUCCEEDED':
                break
            elif state in ['QUEUED', 'RUNNING']:
                time.sleep(wait_time)
                wait_time = min(wait_time * 2, max_wait)  # Double wait time, cap at max_wait
        # Retrieve results
        results = athena.get_query_results(QueryExecutionId=query_execution_id)
        return results

  6. Choose Deploy.

The code provided for the Lambda function includes some placeholders that you will replace later, after you have the required information. Don’t test the Lambda function at this time because it will fail because of the presence of the placeholders.

Create a user with administrative access

Amazon SageMaker Unified Studio supports two distinct domain types: AWS IAM Identity Center based domains and IAM based domains. At the time of writing this post, only IAM Identity Center based domains support multi-accounts association, therefore in this post you work with this type of domain that requires IAM Identity Center.

In the governance account, you enable IAM Identity Center and create an administrative user to create and manage the Amazon SageMaker Unified Studio domain. Create a user with administrative access:

  1. Enable IAM Identity Center in the governance account. For instructions, refer to Enable IAM Identity Center.
  2. In IAM Identity Center in the governance account, grant administrative access to a user. For a tutorial about using the IAM Identity Center directory as your identity source, refer to Configure user access with the default IAM Identity Center directory.

Sign in as the user with administrative access:

  • To sign in with your IAM Identity Center user, use the sign-in URL that was sent to your email address when you created the IAM Identity Center user. For help signing in using an IAM Identity Center user, refer to Sign in to your AWS access portal.

Create a SageMaker Unified Studio domain

To create the Amazon SageMaker Unified Studio domain in the governance account refer to Create a Amazon SageMaker Unified Studio domain – quick setup.

After your domain is created, you can navigate to the Amazon SageMaker Unified Studio portal (a browser-based web application) where you can use your data and configured tools for analytics and AI. Save the Amazon SageMaker Unified Studio portal URL because you will use this URL later.

Solution steps

Now that you have the prerequisites in place, you can complete the following ten high-level steps to implement the solution.

Associate the producer and consumer accounts to the Amazon SageMaker Unified Studio domain

Start by associating the producer and consumer accounts to the newly created Amazon SageMaker Unified Studio domain. When you associate your producer and consumer accounts to the domain, make sure to select IAM users and roles can access APIs and IAM users can log in to Amazon SageMaker Unified Studio in the AWS RAM share managed permission section. For step-by-step instructions, refer to Associated accounts in Amazon SageMaker Unified Studio. If your AWS accounts are part of the same organization, your association requests are automatically accepted. However, if your AWS accounts aren’t part of the same organization, request association with the other AWS accounts in the governance account and then accept the association request in both the producer and consumer accounts.

Create two project profiles

Now, create two project profiles, one for the producer project and one for the consumer project.

In Amazon SageMaker Unified Studio, a project profile defines an uber template for projects in your Amazon SageMaker domain. A project profile is a collection of blueprints that provides reusable AWS CloudFormation templates used to create project resources.

A project profile is associated to a specific AWS account. This means, when a project is created the blueprints listed in the project profile are deployed in the associated AWS account. To use a project profile, you must enable its blueprints in the AWS account associated to the project profile.

Create the producer project profile

You’re going to create the producer project profile that is associated to the producer account. This project profile will be used to create the producer project. This profile includes by default the Tooling blueprint that creates resources for the project, including IAM user roles and security groups.

Before creating the project profile, you will enable the Tooling blueprint in the producer account using the following procedure:

  1. Access the SageMaker console in the producer account.
  2. In the navigation pane, choose Associated domains.
  3. Select the domain you created while setting up.
  4. On the Blueprints tab, choose Enable in the Tooling blueprint section as shown in the following image:
  5. SageMaker Unified Studios Tooling blueprint config: disabled status with Enable button for IAM roles & AWS resource setup

  6. For Virtual private cloud (VPC) select your account VPC.
  7. For Subnets, select at least two subnets in different Availability Zones.
  8. Choose Enable blueprint.

Proceed to creating the project profile in the governance account:

  1. Access the SageMaker console in the governance account.
  2. In the navigation pane, choose Domains.
  3. Select the domain you created as part of prerequisites.
  4. Under the Project profiles tab, choose Create and enter the following information:
    1. For Project profile name, enter producer-project-profile.
    2. For Project profile creation options, select Custom create.
    3. DO NOT SELECT A BLUEPRINT for Blueprints because the Tooling blueprint is included by default in any project profile.
    4. For Account, select Provide an account ID.
    5. For Account ID, enter the producer account ID.
    6. For Region, select Provide region name and then select the Region in which you’re working.
    7. For Authorization, select Allow all users and groups.
    8. For Project profile readiness, select Enable project profile on creation.
  5. Choose Create project profile.

Create a consumer project profile

You also create a consumer project profile and associate it to the consumer account. This profile will be used to create the consumer project. The consumer project profile includes the LakeHouseDatabase blueprint, which is needed to create a lakehouse environment with an AWS Glue database for data management and an Amazon Athena workgroup for querying. The Tooling blueprint is included by default in the project profile.

Before creating the project profile, enable the Tooling and LakeHouseDatabase blueprints in the consumer account:

  1. Access the SageMaker console in the consumer account.
  2. In the navigation pane, choose Associated domains.
  3. Select the domain you created as part of prerequisites.
  4. On the Blueprints tab, choose Enable in the Tooling blueprint section.
  5. For Virtual private cloud (VPC) select your account VPC.
  6. For Subnets, select at least two subnets in different Availability Zones.
  7. Choose Enable blueprint.
  8. In the navigation pane, choose Associated domains.
  9. Select the domain you created as part of prerequisites.
  10. Under the Blueprints tab, select the LakeHouseDatabase blueprint.
  11. Choose Enable.
  12. Choose Enable blueprint.

After blueprints are enabled in the consumer account, you can proceed creating the project profile:

  1. Access the SageMaker console in the governance account.
  2. In the navigation pane, choose Domains.
  3. Select the domain you created as part of prerequisites.
  4. Under Project profiles tab choose Create and enter the following information:
    1. For Project profile name, enter consumer-project-profile.
    2. For Project profile creation options, select Custom create.
    3. For Blueprints, select LakeHouseDatabase.
    4. For Account, select Provide an account ID.
    5. For Account ID, enter the consumer account ID.
    6. For Region, select Provide region name and then select the Region you are working.
    7. For Authorization, select Allow all users and groups.
    8. For Project profile readiness, select Enable project profile on creation.
  5. Choose Create project profile.

Create SageMaker Unified Studio producer and consumer projects

In Amazon SageMaker Unified Studio, a project is a boundary within a domain where you can collaborate with other users to work on a business use case. In projects, you can create and share data and resources.To create producer and consumer projects in Amazon SageMaker Unified Studio use the following instructions:

  1. Access the Amazon SageMaker Unified Studio portal.
  2. Choose the Select a project dropdown list.
  3. Choose Create project and enter the following information:
    1. For Project name, enter Producer.
    2. For Project profile, select producer-project-profile.
  4. Choose Continue.
  5. Choose Continue.
  6. Choose Create project.

After you’ve created the Producer project, note in a text file the Project role ARN that is displayed in the Project overview. The following image is shown for reference. The project role name is the string that follows arn:aws:iam::<account_ID>:role/ in the project role Amazon Resource Name (ARN). You will use both project role name and ARN later.

SageMaker Producer project overview: active status, files listed, S3 location & IAM role ARN displayed in project details tab

Repeat the preceding procedure to create the Consumer project. Be sure to enter Consumer for Project name and then select consumer-project-profile for Project profile. After it’s created, note the Project role ARN in a text file. The project role name is the string that follows arn:aws:iam::<account_ID>:role/ in the project role ARN. You will use both project role name and ARN later.

Bring your own data from the producer account

Bring your own data to the Amazon SageMaker Unified Studio Producer project. AWS provides several options to achieve this onboarding. The first option is automated onboarding in Amazon SageMaker lakehouse, in which you ingest the Amazon SageMaker lakehouse metadata of datasets into Amazon SageMaker Catalog. With this option, you can onboard your Amazon SageMaker lakehouse data as part of creating a new Amazon SageMaker Unified Studio domain or for an existing domain.

For more information about automated onboarding of Amazon SageMaker lakehouse data, refer to Onboarding data in Amazon SageMaker Unified Studio. As other options, you can bring in existing resources to your Amazon SageMaker Unified Studio project by using the Data and Compute pages in your project, or by using scripts provided in GitHub. For more information about using the Data and Compute pages or about using scripts, refer to Bringing existing resources into Amazon SageMaker Unified Studio. In this post, you will use Amazon SageMaker lakehouse capabilities to import your trees AWS Glue table into the Producer project.

Register the Amazon S3 location for the table

To use Lake Formation permissions for fine-grained access control to the trees table, you need to register in Lake Formation the Amazon S3 location of the trees table. To do that, complete the following actions:

  1. Access the Lake Formation console in the producer account.
  2. In the navigation pane under Administration, choose Data lake locations.
  3. Choose Register location and enter the following information:
    1. For S3 URI, enter s3://<bucket-name>/<prefix>/ where <bucket-name> is the name of the S3 bucket you created in the prerequisites and <prefix> is the optional prefix for the trees.csv file you uploaded as part of the prerequisite.
    2. For IAM role, select AWSServiceRoleForLakeFormationDataAccess.
    3. For Permission mode, select Lake Formation.
  4. Choose Register location.

Grant Producer project role permissions on the database

Grant database access to the IAM role that is associated with your Producer project. This role is called the project role, and it was created in IAM upon project creation.

To access the AWS Glue Data Catalog collections database from the Producer project in the Amazon SageMaker Unified Studio, complete the following actions:

  1. Access the Lake Formation console in the producer account.
  2. In the navigation pane under Data Catalog, choose Databases.
  3. Choose the collections database.
  4. From the Actions menu, choose Grant and enter the following information:
    1. For IAM users and roles, select your Producer project’s role name. This is the string starting with datazone_usr_role_ that is part of the Producer project role ARN that you noted in step 3 “Create SageMaker Unified Studio producer and consumer projects”.
    2. For Database permissions, select Describe.
  5. Choose Grant.

Grant Producer project role permissions on the table

Grant trees table access to the IAM role that is associated with your Producer project. To grant these permissions use the following instructions:

  1. Access the Lake Formation console in the producer account.
  2. In the navigation pane under Data Catalog, choose Tables and MVs.
  3. Select the trees table.
  4. From the Actions menu, choose Grant and enter the following information:
    1. For IAM users and roles, select your Producer project’s role. This is the string starting with datazone_usr_role_ that is part of the Producerproject role ARN that you noted in step 3 “Create SageMaker Unified Studio producer and consumer projects”.
    2. For Table permissions, select Select and Describe.
    3. For Grantable permissions, select Select and Describe.
  5. Choose Grant.

Revoke any existing permissions of IAMAllowedPrincipals

You must revoke the IAMAllowedPrincipals group permissions on both the database and table to enforce Lake Formation permission for access. For more information, refer to Revoking permission using the Lake Formation console.

  1. Access the Lake Formation console in the producer account.
  2. In the navigation pane under Permission, choose Data permissions.
  3. Select the entries where Principal is set to IAMAllowedPrincipals and Resource is set to collections or trees as in the following image:
  4. Data permissions table: 2 of 5 IAMAllowedPrincipals entries selected. All permissions granted for collections DB & trees table

  5. Choose Revoke.
  6. Enter revoke.
  7. Choose Revoke again.

Verify that data is available in the Producer project

Verify that your collections database and trees table are accessible in the Producer project:

  1. Access the Amazon SageMaker Unified Studio portal.
  2. Choose the Select a project drop-down menu and choose the Producer project.
  3. In the navigation pane under Overview, choose Data.
  4. Choose Lakehouse.
  5. Choose AwsDataCatalog.
  6. Choose collections.
  7. Choose tables.
  8. Choose the three-dot action menu next to your trees table and choose Preview data, as shown in the following image.
    AWS Data Catalog interface: collections database in Lakehouse with trees table, presenting preview/notebook/drop options
  9. You’ll find data from the trees table as shown in the following image.
    Query Editor showing SQL query on trees table with results: oak (3 stars), maple (2), birch (3). Red arrow highlights output

Create Amazon SageMaker Catalog asset

Even if it’s accessible in the project, to work with the trees table in Amazon SageMaker Catalog, you need to register the data source and create an Amazon SageMaker Catalog asset:

  1. Access the Amazon SageMaker Unified Studio portal.
  2. Choose the Select a project dropdown list and choose the Producer project.
  3. On the project page, under Project catalog in the navigation pane, choose Data sources.
  4. Choose Create Data Source and make the following selections:
    1. For Name, enter collections.
    2. For Data source type, select AWS Glue (Lakehouse).
    3. For Database name, select collections.
    4. Choose Next.
    5. Choose Next.
    6. Choose Next.
    7. Choose Create.
  5. After the data source is created, you will be in the collections data source page, choose Run. This will import metadata and create the Amazon SageMaker Catalog asset.
  6. In the collections data source, on the Data source runs tab, you’ll find your run marked as Completed and the trees asset Successfully created, as shown in the following image:
    Producer project Assets page: Inventory tab presenting trees Glue Table asset with red arrows highlighting navigation & selection

Publish the data asset in the Amazon SageMaker Catalog

Publishing a data asset manually is a one-time operation that you need to perform to allow others to access the data asset through the catalog:

  1. Access the Amazon SageMaker Unified Studio portal.
  2. Choose the Select a project dropdown list and choose the Producer project.
  3. On the project page under Project catalog, choose Assets.
  4. Select your trees data asset that is available on the Inventory tab. The following image is shown for reference.
    Assets Inventory page: trees Glue Table listed in Producer project with navigation arrows highlighting menu selection
  5. (Optional) If automated metadata generation is enabled when the data source is created, metadata for assets (such as the asset business name) is available to review and accept or reject. You can either choose Accept All or Reject All in the Automated Metadata Generation banner.
  6. Choose Publish Asset. The following image is shown for reference.
    Asset overview: Agricultural Crop Yield dataset with automated metadata banner, ACCEPT ALL & PUBLISH ASSET buttons highlighted
  7. Choose Publish Asset.

Subscribe to the data asset in the Amazon SageMaker Catalog

To consume data assets in the Consumer project, subscribe to the data asset by creating a subscription request:

  1. Access the Amazon SageMaker Unified Studio portal.
  2. Choose the Select a project dropdown list and choose Consumer project.
  3. On the Discover menu, choose Catalog.
  4. Enter trees in the search box and then select the data asset returned from the search. If in step 7 “Publish the data asset in the Amazon SageMaker Catalog” you chose Accept All in the Automated Metadata Generation banner, your data asset will have a different business name generated by the automated metadata recommendations feature. The data asset technical name is trees. For reference, refer to the following image.
    Data Catalog search: 'trees' query shows Agricultural Crop Yield dataset with browse assets & data products options
  5. Choose Subscribe.
  6. For Comment, enter a justification such as This data asset is needed for model training purposes.
  7. Choose Subscribe again.

By default, asset subscription requests require manual approval by a data owner. However, if the requester in the Consumer project is also a member of the Producer project, the subscription request is automatically approved. For information about approving subscription requests, refer to Approve or reject a subscription request in Amazon SageMaker Unified Studio.

Configure your Lambda IAM role to access the subscribed data access

To enable your Lambda function access to the subscribed data asset, you need to allow the Lambda function to assume the Consumer project role. To do this, edit the Consumer project’s IAM role trust relationship:

  1. Navigate to the IAM console in the consumer account.
  2. In the navigation pane under Access management, choose Roles.
  3. Select the Consumer project’s IAM role. This is the string starting with datazone_usr_role_ that is part of the Consumer project role ARN that you noted in step 3 “Create SageMaker Unified Studio producer and consumer projects”.
  4. Under the Trust relationships tab, choose Edit trust policy.
  5. For backup reasons, make a copy of the existing trust policy in a text file.
  6. In the Edit trust policy window, add the following statement to the existing trust policy without removing or overwriting other existing statements in the trust policy. Be sure to replace the placeholder <account_id> with your consumer AWS account ID.
    {
        "Effect": "Allow",
        "Principal": {
            "AWS": "arn:aws:iam::<account_id>:role/smus_consumer_lambda"
        },
        "Action": [
            "sts:AssumeRole"
        ]
    }	

    IAM trust policy editor: JSON code with red arrow highlighting AWS principal ARN for smus_consumer_lambda role

  7. Choose Update policy.

Test the Lambda function’s access to the subscribed data asset

Before you can test your Lambda function, you need to replace placeholders in the function code and in the IAM policy. There are three placeholders to be replaced: <role_arn>, <database_name> and <workgroup_id>. For <role_arn>, you already have the actual value, which is the Consumer project’s role ARN that you noted in step 3 “Create SageMaker Unified Studio producer and consumer projects”. The next sections provide instructions to retrieve values for the other placeholders.

Retrieve the AWS Glue Data Catalog database name

You need to find the name of the AWS Glue Data Catalog database that was created along with the Consumer project. You will then use this value to replace the <database_name> placeholder in the consumer_function Lambda function code. To retrieve the AWS Glue Data Catalog database name, follow these instructions:

  1. Access the Amazon SageMaker Unified Studio portal.
  2. Choose the Select a project dropdown list and choose Consumer project.
  3. On the project page, under Overview, choose Data.
  4. Choose Lakehouse.
  5. Choose AwsDataCatalog.
  6. Copy the name of the database. It should be an alphanumerical string starting with glue_db, as in the following image:
  7. Consumer project Data page: Lakehouse > AwsDataCatalog > glue_db database navigation with tables & views expandable sections” width=”1084″ height=”294″> </p>
</ol>
<h4>Retrieve the Athena workgroup ID</h4>
<p>You need to find the ID of the Athena workgroup that was created along with the <code>Consumer</code> project. You will then use this value to replace the <code><workgroup_id></code> placeholder in the <code>consumer_function</code> Lambda function code and in the <code>smus_consumer_athena_execution</code> IAM policy. Use the following instructions to retrieve the Athena workgroup ID:</p>
<ol>
<li>Access the Amazon SageMaker Unified Studio portal.</li>
<li>Choose the <strong>Select a project</strong> dropdown list and choose <code>Consumer</code> project.</li>
<li>On the project page, under <strong>Overview</strong>, choose <strong>Compute</strong>.</li>
<li>Under the <strong>SQL analytics</strong> tab, select <strong>project.athena</strong>, as in the following image:<br /> <img decoding=

  8. Copy the Workgroup ARN and save to a text file. The Athena workgroup ID is the string that follows arn:aws:athena:<region>:<account_ID>:workgroup/ in the Workgroup ARN.

Replace placeholder in the smus_consumer_athena_execution IAM policy

To replace the <workgroup_id> placeholder in the smus_consumer_athena_execution IAM policy, use the following procedure:

  1. Access the IAM console in the consumer account.
  2. In the navigation pane, choose Policies.
  3. In the search field enter smus_consumer_athena_execution.
  4. Select the smus_consumer_athena_execution policy.
  5. Choose Edit.
  6. Replace <workgroup_id> with the value you noted earlier.
  7. Choose Next.
  8. Choose Save changes.

Replace placeholders in the Lambda function code and test it

In this section, you will replace the <role_arn>, <database_name> and <workgroup_id> placeholders in the consumer_function Lambda function code, and then you can test the function ability to access data of the trees table.

  1. Access the Lambda console in the consumer account.
  2. In the navigation pane, choose Functions.
  3. Select consumer_function.
  4. Under the Code tab, replace <role_arn>, <database_name> and <workgroup_id> placeholders with the respective values you noted earlier.
  5. Choose Deploy.
  6. Under the Test tab, for Event name, enter mytest.
  7. Choose Test.
  8. Choose Details in the green banner titled Executing function that appears after the execution is completed.
  9. The execution log reports the trees table content, as shown in the following image:
    Lambda test results: consumer_function succeeded with JSON output showing VarCharValue 'ok' and '3', execution details available

If your Lambda function execution fails due to timeout, change the function timeout setting as follows:

  1. Access the Lambda console in the consumer account.
  2. In the navigation pane, choose Functions.
  3. Select consumer_function.
  4. Under the Configuration tab, choose Edit.
  5. For Timeout, enter 15 sec or a greater value.
  6. Choose Save.

After increasing the timeout, test the function again.

Clean up

If you no longer need the resources you created as you followed this post, delete them to prevent incurring additional charges. Start by deleting your Amazon SageMaker Unified Studio domain in the governance account. For more information, refer to Delete domains.

To remove the AWS Glue collections database from the producer account, follow these steps:

  1. Access the Glue console in the producer account.
  2. In the navigation pane under Data Catalog, choose Databases.
  3. Select the collections database.
  4. Choose Delete.
  5. Choose Delete.

To remove the S3 bucket from the producer account, empty the bucket and then you can delete the bucket. For information about emptying the bucket, refer to Emptying a general purpose bucket. For information about deleting the bucket, refer to Deleting a general purpose bucket.

To remove the Lambda function from the consumer account, follow these steps:

  1. Access the Lambda console in the consumer account.
  2. In the navigation pane, choose Functions.
  3. Select the consumer_function Lambda function.
  4. Choose the Actions menu and then choose Delete function.
  5. Enter confirm.
  6. Choose Delete.

To complete the cleanup, delete the IAM role named smus_consumer_lambda, then delete the IAM policy named smus_consumer_athena_execution in the consumer account. For information about removing a IAM role, refer to Delete roles or instance profiles. For information about removing an IAM policy, refer to Delete IAM policies.

Conclusion

In this post, we covered adopting Amazon SageMaker Catalog for data governance without rearchitecting your existing applications and data repositories. We walked through how to onboard existing data in Amazon SageMaker Unified Studio, then publish it in a catalog, and then subscribe and consume the data from resources deployed outside the context of an Amazon SageMaker Unified Studio project. This solution can help you accelerate your implementation of a data mesh pattern with Amazon SageMaker Catalog to publish, find, and access data securely in your organization.
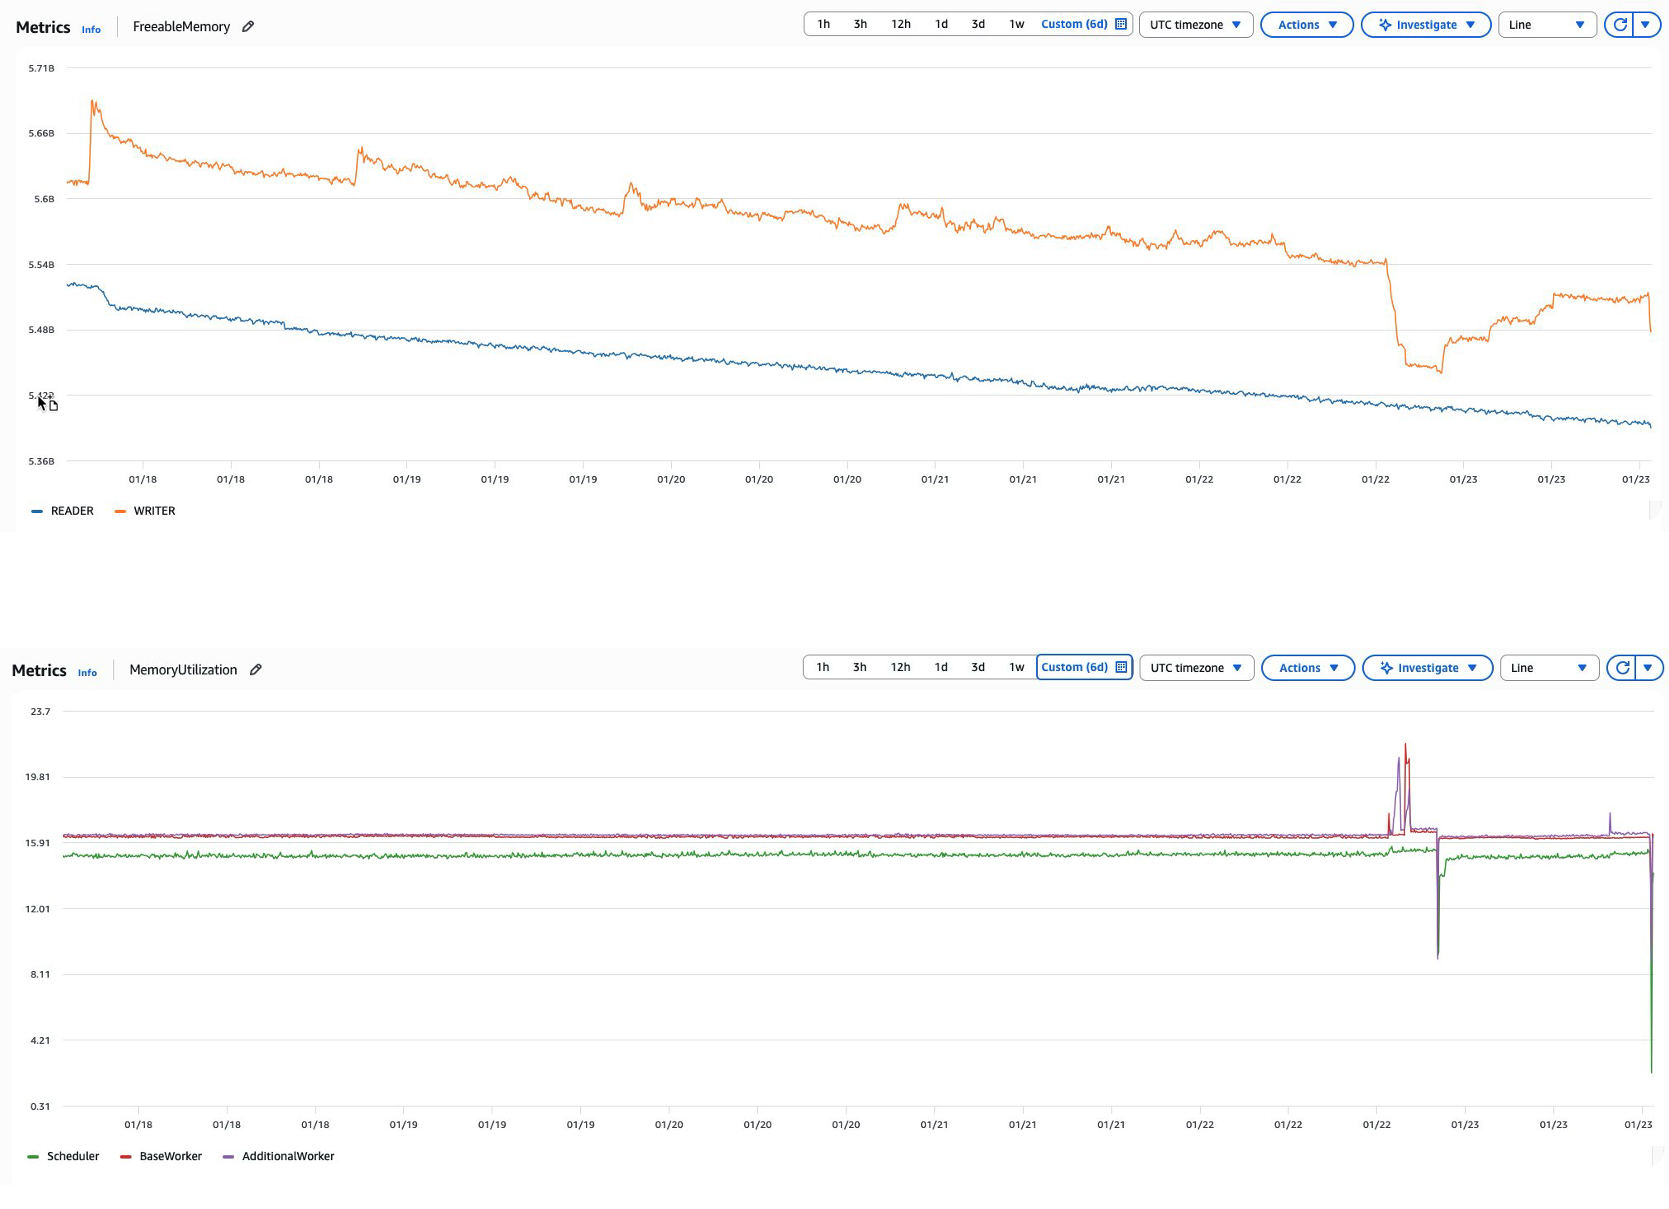
For more information, refer to What is Amazon SageMaker? and work through the Amazon SageMaker Workshop to try the unified experience for data, analytics, and AI.


About the authors

Paolo Romagnoli

Paolo is a Senior Solutions Architect at AWS for Energy and Utilities. With 20+ years of experience in designing and building enterprise solutions, he works with global energy customers to design solutions to address customers’ business and technical needs. He is passionate about technology and enjoys running.

Joel Farvault

Joel is a Principal Specialist SA Analytics for AWS with 25 years’ experience working on enterprise architecture, data governance and analytics. He uses his experience to advise customers on their data strategy and technology foundations.

How CyberArk uses Apache Iceberg and Amazon Bedrock to deliver up to 4x support productivity

Post Syndicated from Moshiko Ben Abu original https://aws.amazon.com/blogs/big-data/how-cyberark-uses-apache-iceberg-and-amazon-bedrock-to-deliver-up-to-4x-support-productivity/

This post is co-written with Moshiko Ben Abu, Software Engineer at CyberArk.

CyberArk achieved up to 95% reduction in case resolution time using Amazon Bedrock and Apache Iceberg.

This improvement addresses a challenge in technical support workflow: when a support engineer receives a new customer case, the biggest bottleneck is often not diagnosing the problem but preparing the data. Customer logs arrive in different formats from multiple vendors, and each new log format typically requires manual integration and correlation before an investigation can begin. For simple cases, this process can take hours. For more complex investigations, it can take days, slowing resolution and reducing overall engineer productivity.

CyberArk is a global leader in identity security. Centered on intelligent privilege controls, it provides comprehensive security for human, machine, and AI identities across business applications, distributed workforces, and hybrid cloud environments.

In this post, we show you how CyberArk redesigned their support operations by combining Iceberg’s intelligent metadata management with AI-powered automation from Amazon Bedrock. You’ll learn how to simplify data processing flows, automate log parsing for diverse formats, and build autonomous investigation workflows that scale automatically.

To achieve these results, CyberArk needed a solution that could ingest customer logs, automatically structure them, establish relationships between related events, and make everything queryable in minutes, not days. The architecture had to be serverless to handle unpredictable support volumes, secure enough to protect customer Personally Identifiable Information (PII), and fast enough to allow same day case resolution.

The legacy architecture: Bottlenecks and manual workflows

When support engineers received customer cases, they would upload log files to the data lake stored in Amazon Simple Storage Service (Amazon S3). The original design then suffered from the complexity of multi-step raw data processing.

First, CyberArk’s custom parsing logic running on AWS Fargate would parse these uploaded log files and transform the raw data. During this stage, the system also had to scan for PII and mask sensitive data to protect customer privacy.

Next, a separate process converted the processed data into Parquet format.

Finally, AWS Glue crawlers were required to discover new partitions and update table metadata for processed Parquet files. This dependency became the most complex and time-consuming part of the pipeline. Crawlers ran as asynchronous batch jobs rather than in real time, often introducing delays of minutes to hours before support engineers could query the data.

But the inefficiency went deeper than just architectural complexity. CyberArk supports customers running diverse product environments across multiple vendors. Each vendor and product produces logs in different formats with unique schemas, field names, and structures. Adding support for a new vendor meant days of integration work to understand their log format and build custom parsers.

CyberArk Legacy Logs Ingestion Flow

Figure 1: Legacy log ingestion architecture diagram showing the flow from S3 upload through AWS Fargate processing with AWS Glue Crawler

Beyond ingestion, the investigation process itself was manual and time consuming. Support engineers would manually query data, correlate events across different log sources, search through product documentation, and piece together root cause analysis through trial and error. This process required deep product expertise and could take hours or days depending on issue complexity. The new architecture addresses these inefficiencies through three key innovations:

  1. Single stage serverless processing: AWS Fargate with PyIceberg directly creates Iceberg tables from raw logs in one pass, removing intermediate processing steps and crawler dependencies entirely.
  2. AI powered dynamic parsing: Amazon Bedrock automatically generates grok patterns for log parsing by analyzing file schemas, transforming what was once a manual, time consuming process into a fully automated workflow.
  3. Autonomous investigation with AI Agents: AI Agents autonomously perform complete root cause analysis by querying log data, analyzing product knowledge bases, identifying event flows, and recommending solutions, transforming hours of manual investigation into minutes of automated intelligence.

The solution: AI-powered automation meets single-stage Iceberg processing

The new system delivers zero touch log processing from upload to query. Support engineers simply upload customer log ZIP files to the system. Here’s where the transformation happens: CyberArk’s custom processing logic still runs on AWS Fargate, but now it uses Amazon Bedrock to intelligently understand the data.

Zero-touch log processing workflow

The system extracts sample log entries from the uploaded log files and sends them to Amazon Bedrock along with context about the log source and table schema from AWS Glue Data Catalog. Amazon Bedrock analyzes the samples, understands the structure, and automatically generates grok patterns optimized for the specific log format.

Grok patterns are structured expressions that define how to extract meaningful fields from unstructured log text. For example, the following grok pattern specifies that a timestamp appears first, followed by a severity level, then a message body %{TIMESTAMP_ISO8601:timestamp} %{LOGLEVEL:severity} %{GREEDYDATA:message}

The system validates these grok patterns against additional samples to verify accuracy before applying them to parse the complete log file. Successfully validated grok patterns are stored in Amazon DynamoDB, creating a repository of known patterns. When the system encounters similar log formats in future uploads, it can retrieve these patterns directly from Amazon DynamoDB, avoiding redundant grok pattern generation. Amazon Bedrock processes log samples in real-time without retaining customer data or using it for model training, maintaining data privacy.

This entire process invokes Claude 3.7 Sonnet model from Amazon Bedrock and is orchestrated by AWS Fargate tasks with retry logic for reliability. The processing uses these AI-generated grok patterns to parse the logs and create or update Iceberg tables using PyIceberg APIs without human intervention.

This automation reduced logs onboarding time from days to minutes, enabling CyberArk to handle diverse customer environments without manual intervention.

Figure 2: Log ingestion architecture diagram showing the flow from S3 upload through AWS Fargate processing with Amazon Bedrock integration to Iceberg table creation

Figure 2: Log ingestion architecture diagram showing the flow from S3 upload through AWS Fargate processing with Amazon Bedrock integration to Iceberg table creation

Apache Iceberg: Simplified architecture, faster queries

Iceberg simplified and improved CyberArk’s data lake architecture by addressing the two primary bottlenecks in the legacy system: slow schema management and inefficient query performance.

Built-in schema evolution removes crawler dependency

In the legacy architecture, AWS Glue crawlers became a source of operational overhead and latency. Even when triggered on demand, crawlers ran as batch jobs over S3 prefixes to discover partitions and update metadata. As data volumes grew and datasets diversified across vendors and schemas, teams had to manage and operate a growing number of crawler jobs. The resulting delays, often ranging from minutes to hours, slowed data availability and downstream investigation workflows.

Iceberg removes this entire layer of complexity. Iceberg’s intelligent metadata layer automatically tracks table structure, schema changes, and partition information as data is written. When CyberArk’s processing creates or updates Iceberg tables through PyIceberg, the metadata is updated instantly and atomically. There’s no waiting for crawlers jobs to complete, and no risk of stale metadata. The moment data is written, it’s immediately queryable in Amazon Athena.

PyIceberg: Making Iceberg accessible beyond Apache Spark

Working with Iceberg usually involved Apache Spark and the complexity of distributed data processing. PyIceberg changed that by letting CyberArk create and manage Iceberg tables using a simple Python library. CyberArk’s data engineers could write straightforward Python code running on AWS Fargate to create Iceberg tables directly from parsed logs, without spinning up Spark clusters.

This accessibility was essential for CyberArk’s serverless architecture. PyIceberg enabled single stage processing where AWS Fargate tasks could parse logs, apply PII masking, and create Iceberg tables in one pass. The result was simpler code and lower operational overhead.

Metadata-driven query optimization delivers speed

In addition to removing crawlers, Iceberg significantly improved query performance through its intelligent metadata architecture. Iceberg maintains detailed statistics about data files, including min/max values, null counts, and partition information. When support engineers query data in Athena, Iceberg’s metadata layer supports partition pruning and file skipping, making sure queries only read the specific files containing relevant data. For CyberArk’s use case, where tables are partitioned by case ID, this means a query for a specific support case only reads the files for that case, ignoring potentially thousands of irrelevant files. This metadata driven optimization reduced query execution time from minutes to seconds, allowing support engineers to interactively explore data rather than waiting for results.

ACID transactions maintain data consistency

In a multi user support environment where multiple engineers may be analyzing overlapping cases or uploading logs simultaneously, data consistency is essential. Iceberg’s ACID transaction support helps verify that concurrent writes do not corrupt data or create inconsistent states. Each table update is atomic, isolated, and durable, providing the reliability CyberArk needed for production support operations.

Time travel enables historical analysis

Iceberg’s built-in versioning allows support engineers to query historical states of data, essential for understanding how customer issues evolved over time. If an engineer needs to see what the logs looked like when a case was first opened versus after a customer applied a patch, Iceberg’s time travel capabilities make this straightforward. This feature proved essential for complex troubleshooting scenarios where understanding the timeline of events was critical to resolution.

Automated table optimization with AWS Glue

Iceberg tables require periodic maintenance to maintain query performance.

CyberArk enabled AWS Glue automatic table optimization for their Iceberg tables, which handles compaction and expired snapshot cleanup in the background.

For CyberArk’s continuous upload workflow, this automation avoids performance degradation over time. Tables stay optimized without manual intervention from the engineering team.

AI Agents: Autonomous investigation workflow

While the Claude 3.7 Sonnet model from Amazon Bedrock automates grok pattern generation for log ingestion, the more advanced use of Amazon Bedrock comes in the investigation workflow. We use AI agents with Bedrock models to change how support engineers analyze and resolve customer issues.

From manual analysis to AI powered investigation

In the legacy workflow, support engineers would manually query data, correlate events across different log sources, search through product documentation, and piece together root cause analysis through trial and error. This process required deep product expertise and could take hours or days depending on issue complexity. AI Agents automate this entire investigation process. Support engineers use an internal portal to ask questions in natural language about customer issues, questions like
“Show me authentication errors for case 12345 in the last 24 hours”, “What were the most common errors across cases opened this week?” or “Compare the error patterns between case 12345 and case 12346.”

Behind the scenes, the system fires specialized AI Agents that autonomously perform thorough analysis.

How support agents work

Each AI Agent operates as an intelligent investigator with a clear mission: understand what happened, determine why it happened, and recommend how to fix it. When a support engineer asks a question, the agent collects relevant data by querying Athena to retrieve log data from Iceberg tables, filtering for the specific case and time period relevant to the investigation. The agent then accesses CyberArk’s internal knowledge base for the specific product involved, understanding known issues, common error patterns, and documented solutions. The agent then performs the following analysis:

  • Flow identification: Analyzes the sequence of events in the logs to understand what actually happened during the customer’s issue
  • Root cause determination: Correlates log events with product knowledge to identify the underlying cause of the problem
  • Solution recommendations: Suggests specific remediation steps based on the root cause analysis and known resolution patterns

This entire process happens in minutes, delivering advanced analysis that would have taken support engineers hours to perform manually.

For complex cases where a solution is not found, the support agent escalates to another, specialized agent that interacts with service engineers to collect additional inputs and expertise. This human-in-the-loop approach makes sure that even the most challenging cases receive appropriate attention while still benefiting from the automated investigation workflow. The insights gathered from these escalated cases are automatically fed back into CyberArk’s knowledge base, continuously improving the system’s ability to handle similar issues autonomously in the future.

Amazon Bedrock never shares customer data with model providers or uses it to train foundation models, case data and investigation insights remain within CyberArk’s environment.

Concurrent agent execution at scale

When multiple support engineers investigate different cases simultaneously, the solution runs specialized agents concurrently. CyberArk currently uses Claude 3.7 Sonnet as the foundation model for these agents. Each agent works independently on its assigned investigation, operating in parallel without resource contention. This concurrent execution allows the investigation workflow to scale automatically with support volume, handling peak loads without performance degradation.

AI-powered investigation advantage

This AI-powered investigation workflow delivers two key advantages.

Investigations that took hours now complete in minutes, enabling support engineers to resolve up to 4x more cases per day.

The system also creates a continuous learning feedback loop. When cases require manual resolution by engineers, these resolutions are automatically recorded and fed back into the knowledge base. Future investigations benefit from this accumulated expertise, with agents applying lessons learned from previous manual resolutions to similar cases. Amazon Bedrock doesn’t use customer data to train foundation models. Case data and investigation insights remain within CyberArk’s environment.
This automated feedback mechanism means the investigation workflow becomes more effective over time, continuously improving resolution accuracy and speed.

CyberArk - AI Powered Logs Investigation Flow

Figure 3: Investigation workflow diagram showing natural language query through AI Agents to Athena queries and knowledge base analysis

Scaling without proportional engineering growth

The business impact of this AI automation is significant. CyberArk can expand its vendor coverage and product portfolio without adding data engineering headcount. The same system that handles today’s log types will automatically handle tomorrow’s additions, whether that’s ten new formats or thousands, significantly reducing time to market for new product and vendor integrations.

The results: Significant improvements in resolution time and productivity

The transformation delivered measurable improvements across every key metric.

Resolution time: CyberArk achieved up to 95% reduction in time from case assignment to resolution. Simple cases that used to take 4 to 6 hours now take just 15 to 30 minutes. Complex cases that previously took up to 15 days are now completed in 2 to 4 hours.

Engineer productivity: Support engineers now handle 8 to 12 cases per day, compared to just 2 to 3 cases before. This means each engineer is helping up to 4x more customers.

Data availability: Logs are queryable within minutes of upload instead of waiting hours or days. Support engineers can start investigating issues almost immediately after receiving customer data.

Operational efficiency: The system requires zero manual intervention for new log formats or schema changes. Cases that used to require days of data engineering work now happen automatically.

Cost optimization: The serverless architecture alleviated idle infrastructure costs while scaling automatically with demand. CyberArk only pays for what they use, when they use it.

Customer satisfaction: Faster resolution times and proactive issue identification significantly improved the customer experience. Problems get solved in hours instead of days, and customers spend less time waiting for answers.

What’s next?

While AWS continues to innovate across both data lake management and agentic AI infrastructure, the following capabilities align well with CyberArk’s architecture and may offer additional operational benefits as the system scale.

Agent infrastructure maturity

As the agent-based architecture scales to handle thousands of concurrent investigations, CyberArk is transitioning to Amazon Bedrock AgentCore for future agent deployments. AgentCore provides a managed runtime for production AI agents with enhanced observability through AWS X-Ray integration, intelligent memory for context retention across sessions, and streamlined operational workflows. While the current AI Agents implementation delivers the performance and reliability CyberArk needs today, AgentCore represents a natural evolution path as operational requirements grow, offering framework-agnostic deployment, automatic scaling, and comprehensive monitoring capabilities without infrastructure management overhead.

Amazon S3 Tables

CyberArk’s current architecture uses Iceberg tables stored in Amazon S3 buckets. Amazon S3 Tables offers fully managed Iceberg tables with built-in optimization.

As CyberArk continue to scale with hundreds of Iceberg tables and rapid data growth, CyberArk is exploring a migration to Amazon S3 Tables to further reduce operational overhead.

S3 Tables remove the need to set up and monitor AWS Glue maintenance jobs. It automatically performs maintenance to enhance the performance of Iceberg tables, including unreferenced file removal, file compaction, and snapshot management. Additionally, S3 Tables provides Intelligent-Tiering that automatically moves data between storage classes based on access patterns, optimizing storage costs without manual intervention.

Because S3 Tables uses Iceberg open table format, migration would not require changes to existing Athena queries and PyIceberg code. This flexibility allows CyberArk to evaluate and adopt S3 Tables when the operational and cost benefits align with their business needs.

Conclusion

CyberArk’s transformation demonstrates how combining modern data lake architecture with AI automation can significantly change operational economics. By combining Iceberg’s intelligent metadata management with AI-powered automation from Amazon Bedrock, CyberArk transformed case resolution from days to minutes while enabling support operations to scale automatically with business growth. Support engineers now spend their time solving customer problems instead of wrangling data, customers receive faster resolutions, and the system scales automatically with the business.

To learn more about Iceberg on AWS, refer to Working with Amazon S3 Tables and table buckets and Using Apache Iceberg on AWS. To learn more about Amazon Bedrock AgentCore, refer to Amazon Bedrock AgentCore.


About the authors

Moshiko Ben Abu

Moshiko Ben Abu

Moshiko is a Software Engineer at CyberArk, specializing in architecting cloud-native applications and building AI-powered solutions. Moshiko advocates for a shift-left approach where security is built in from day one. His drive for innovation has been recognized across the company, earning him the Innovator culture award at CyberArk’s Global Kickoff.

Riki Nizri

Riki Nizri

Riki is a Solutions Architect at AWS. Collaborating with AWS ISV customers, Riki helps them leverage AWS services to build modern, efficient solutions that drive measurable business outcomes.

Sofia Zilberman

Sofia Zilberman

Sofia works as a Senior Streaming Solutions Architect at AWS, helping customers design and optimize real-time data pipelines using open-source technologies like Apache Flink, Kafka, and Apache Iceberg. With experience in both streaming and batch data processing, she focuses on making data workflows efficient, observable, and high-performing.

Build a data pipeline from Google Search Console to Amazon Redshift using AWS Glue

Post Syndicated from Anirudh Chawla original https://aws.amazon.com/blogs/big-data/build-a-data-pipeline-from-google-search-console-to-amazon-redshift-using-aws-glue/

Google Search Console (GSC) is a service offered by Google that helps you monitor, maintain, and troubleshoot your site’s presence in Google Search results. It provides you unique insights directly from Google about how the search engine sees your site, helping you improve your performance in Search Engine Results Pages (SERPs).

When there is a need to merge Google Search Console data with multiple data sources or conduct complex performance analysis, traditional methods can become time-consuming and error-prone. This is where Amazon Redshift and AWS Glue offer a comprehensive data integration solution.

In this post, we explore how AWS Glue extract, transform, and load (ETL) capabilities connect Google applications and Amazon Redshift, helping you unlock deeper insights and drive data-informed decisions through automated data pipeline management. We walk you through the process of using AWS Glue to integrate data from Google Search Console and write it to Amazon Redshift.

Solution overview

AWS Glue is a serverless data integration service that helps discover, prepare, and combine data for analytics, machine learning (ML), and application development. You can use AWS Glue to create, run, and monitor data integration and ETL pipelines and catalog your assets across multiple data stores.

Amazon Redshift is a fast, scalable, and fully managed cloud data warehouse that lets you to process and run complex SQL analytics workloads on structured and semi-structured data. It also helps you securely access your data in operational databases, data lakes, or third-party datasets with minimal movement or copying of data. Tens of thousands of customers use Amazon Redshift to process large amounts of data, modernize their data analytics workloads, and provide insights for their business users.

The following diagram illustrates the architecture that we implement in this post.

Architecture diagram showing AWS Glue data pipeline workflow from Google Search Console to Amazon Redshift, illustrating the ETL process with AWS Glue job reading data from three Google Search Console entities (Search Analytics, Sites, and Sitemaps) and writing to a Redshift provisioned cluster.

The workflow consists of an AWS Glue job reading data from Google Search Console for the three entities that Google Search Console supports (Search Analytics, Sites, and Sitemaps), and writing the data in a Redshift provisioned cluster. AWS Glue supports Google Search Console API v3.

In the following sections, we walk through the following steps to configure AWS Glue to set up a connection between Google Search Console and Amazon Redshift for data migration:

  1. Create an OAuth client.
  2. Create an IAM role for AWS Glue integration with Google Search Console, AWS Secrets Manager, and Amazon Redshift.
  3. Create a secret in Secrets Manager to store the client secret created in the previous step.
  4. Create a connection to Google Search Console in AWS Glue.
  5. Create a connection to Amazon Redshift in AWS Glue.
  6. Set up a table and permissions in Amazon Redshift.
  7. Create an ETL job in AWS Glue.

Prerequisites

Before starting this walkthrough, you must have the following prerequisites in place:

  • An AWS account.
  • A Google Cloud account and a Google Cloud project.
  • In your Google Cloud project, you must enable the Google Search Console API.
    For instructions, see Enable and disable APIs on the API Console Help for Google Cloud Platform.
  • A provisioned cluster or Amazon Redshift Serverless .
    In this post, we use a single-node ra3.large Redshift provisioned cluster deployed in a single Availability Zone. This configuration is used for demonstration purposes only. For production environments, we recommend using multi-node clusters with a minimum of two nodes deployed across multiple Availability Zones for high availability and better performance.
  • An Amazon Simple Service Storage (Amazon S3) bucket.
  • An AWS Identity and Access Management (IAM) role that grants AWS Glue and Amazon Redshift read-only access to Amazon S3. This role will be attached to the Redshift cluster or Redshift Serverless namespace during creation, and will also be used when running the AWS Glue job along with permissions to read and write secrets to Secrets Manager. Refer to the Amazon Redshift Database Developer Guide for more details.

Create OAuth client

To connect to Google Search Console, AWS Glue requires OAuth 2.0 for authentication. You must create an OAuth 2.0 client ID, which AWS Glue uses when requesting an OAuth 2.0 access token. To create an OAuth 2.0 client ID in the Google Cloud Platform console, follow these steps:

  1. On the Google Cloud Platform console, from the projects list, choose a project or create a new one.
  2. If the APIs & Services page isn’t already open, choose the menu icon on the upper left and choose APIs & Services.
  3. In the navigation pane, choose Credentials.
  4. Choose Create Credentials, then choose OAuth client ID.
  5. Select Web application as the application type, enter NewClient as the name, and provide https://console.aws.amazon.com for Authorized JavaScript origins.
  6. For Authorized redirect URIs, add https://us-east-1.console.aws.amazon.com/gluestudio/oauth. This example uses us-east-1 for setting up AWS Glue jobs; change the redirect URIs according to your AWS Region. Multiple redirect URIs can also be specified.
  7. Choose Create.
  8. Open the details page for your new client.
  9. Under Additional information, note down the client ID and client secret. You will need these details when configuring the secret in Secrets Manager.

Create IAM role for AWS Glue integration with Google Search Console, Secrets Manager, and Amazon Redshift

You can use AWS Glue to transfer data from supported sources into your Redshift databases. You need an IAM role because AWS Glue needs authorization to write into Redshift databases. To create a role, complete the following steps:

  1. Sign in to the IAM console with sufficient access to create policies.
  2. Choose Policies in the navigation pane.
  3. Choose Create policy.
  4. On the JSON tab, enter the following policy. AWS Glue needs the following permissions to access and run SQL statements in the Redshift database and create and retrieve secrets with Secrets Manager:
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": [
                    "secretsmanager:DescribeSecret",
                    "secretsmanager:GetSecretValue",
                    "secretsmanager:PutSecretValue",
                    "ec2:CreateNetworkInterface",
                    "ec2:DescribeNetworkInterfaces",
                    "ec2:DeleteNetworkInterface"
                ],
                "Resource": "*"
            },
            {
                "Effect": "Allow",
                "Action": "s3:GetObject",
                "Resource": "arn:aws:s3:::aws-glue-studio-transforms-510798373988-prod-us-east-1/*"
            },
            {
                "Effect": "Allow",
                "Action": [
                    "s3:GetObject",
                    "s3:PutObject"
                ],
                "Resource": [
                    "arn:aws:s3:::aws-glue-assets-testbucket/*"
                ]
            },
            {
                "Sid": "DataAPIPermissions",
                "Effect": "Allow",
                "Action": [
                    "redshift-data:ExecuteStatement",
                    "redshift-data:GetStatementResult",
                    "redshift-data:DescribeStatement"
                ],
                "Resource": "*"
            },
            {
                "Sid": "GetCredentialsForAPIUser",
                "Effect": "Allow",
                "Action": "redshift:GetClusterCredentials",
                "Resource": [
                    "arn:aws:redshift:*:*:dbname:*/*",
                    "arn:aws:redshift:*:*:dbuser:*/*"
                ]
            },
            {
                "Sid": "GetCredentialsForServerless",
                "Effect": "Allow",
                "Action": "redshift-serverless:GetCredentials",
                "Resource": "*"
            },
            {
                "Sid": "DenyCreateAPIUser",
                "Effect": "Deny",
                "Action": "redshift:CreateClusterUser",
                "Resource": [
                    "arn:aws:redshift:*:*:dbuser:*/*"
                ]
            },
            {
                "Sid": "ServiceLinkedRole",
                "Effect": "Allow",
                "Action": "iam:CreateServiceLinkedRole",
                "Resource": "arn:aws:iam::*:role/aws-service-role/redshift-data.amazonaws.com/AWSServiceRoleForRedshift",
                "Condition": {
                    "StringLike": {
                        "iam:AWSServiceName": "redshift-data.amazonaws.com"
                    }
                }
            }
        ]
    }

    Modify the S3 bucket name that you are using as the staging bucket. Additionally, AWS Glue must have access to specific AWS owned S3 buckets for hosting AWS Glue transforms. In this example, the IAM policy uses aws-glue-studio-transforms-510798373988-prod-us-east-1, which is the AWS owned bucket in the us-east-1 Region. Refer to Review IAM permissions needed for ETL jobs for the appropriate bucket name for your Region.

  5. Choose Next.
  6. For Policy name, enter a name (for this post, we use glue-redshift-gsc-policy).
  7. Enter a description, then choose Create policy.
  8. In the navigation pane, choose Roles and Create role.
  9. Choose Custom trust policy and enter the following, then choose Next.
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Principal": {
                    "Service": [
                        "glue.amazonaws.com"
                    ]
                },
                "Action": "sts:AssumeRole"
            }
        ]
    }
    

  10. Search for and select the policy glue-redshift-gsc-policy, then choose Next.
  11. Provide the role name GlueIAMRoleRedshiftNew or another name and relevant Description, then choose Create role.
  12. After the role is created, choose Add permissions and Attach policies.
  13. Search for AWSGlueServiceRole and choose Add Permissions. This policy is typically attached to roles specified when defining crawlers, jobs, and development endpoints.

Screenshot of AWS IAM console showing the policy attachment interface where the AWSGlueServiceRole policy is being added to the GlueIAMRoleRedshiftNew role.

Create secret in Secrets Manager

Complete the following steps to create a Secrets Manager secret:

  1. On the Secrets Manager console, choose Store a new secret.
  2. Select Other type of secret.
  3. For the customer-managed connected application, the secret should contain the connected application’s consumer secret with USER_MANAGED_CLIENT_APPLICATION_CLIENT_SECRET as the key and the client secret value as created in the previous step.
    Screenshot of AWS Secrets Manager console showing the "Store a new secret" interface with "Other type of secret" selected and a key-value pair entry for USER_MANAGED_CLIENT_APPLICATION_CLIENT_SECRET.
  4. Choose Next.
  5. Enter a secret name and choose Next.
  6. Choose Store.

Create connection to Google Search Console in AWS Glue

To create a connection to Google Search Console in AWS Glue, follow these steps:

  1. Sign in to the AWS Glue console with an authorized email ID with permissions already provided in Google Search Console.
  2. In the navigation pane, choose Data connections.
  3. Under Connections, choose Create connection.
  4. In Data sources, search for Google Search Console and choose Next.
    Screenshot of AWS Glue console showing the Data connections page with Google Search Console selected as a data source in the connection creation wizard.
  5. For IAM Role ARN, choose the role created earlier.
  6. For Token URL, use https://oauth2.googleapis.com/token, which is the default value.
  7. For User Managed Client Application ClientId, enter the client ID created earlier while creating the OAuth client.
  8. For AWS Secret, choose the secret created earlier.
  9. If your AWS Glue jobs needs to run in an Amazon virtual private cloud (VPC), provide appropriate details. For more information, refer to Configure a VPC for your ETL job.
    Screenshot of AWS Glue connection configuration form showing fields for IAM Role ARN, Token URL, User Managed Client Application ClientId, AWS Secret selection, and VPC configuration options
  10. Choose Test connection, choose your Google ID, and choose Continue.
    Google account selection dialog prompting the user to choose which Google account to use for authentication with the AWS Glue connection.
  11. Choose Continue to trust the connection.
    Google OAuth consent screen asking the user to continue and trust the connection between AWS Glue and their Google account.

    If the user has authorized access, the connection test will be successful.

    AWS Glue console showing a successful connection test result with a green checkmark indicating the Google Search Console connection was established successfully.

  12. Choose Next.
  13. Provide a connection name and choose Create connection.

Create connection to Amazon Redshift in AWS Glue

Complete the following steps to set up an AWS Glue connection for Amazon Redshift. Refer to Redshift connections for more information.

  1. On the AWS Glue console, in the navigation pane, choose Data connections.
  2. Under Connections, choose Create connection.
  3. In Data sources, search for JDBC and choose Next. For Amazon Redshift, you can also use Redshift connections. In this post, we use JDBC. In this example, we are using a Redshift provisioned cluster.
  4. Provide the Amazon Redshift JDBC URL and either use a Secrets Manager secret for storing credentials or provide the user name and password directly. As a best practice, it is recommended to use Secrets Manager.
  5. Configure network options with Amazon VPC settings for running the AWS Glue job in a VPC. In this example, we use the same VPC, subnet, and security group where the Redshift cluster is provisioned. All JDBC data stores must be accessible from the VPC subnet. A VPC endpoint is required to access Amazon S3 from within your VPC. If your job needs to access both VPC resources and the public internet, configure a NAT gateway in the VPC.Screenshot of AWS Glue connection configuration for Amazon Redshift showing JDBC URL entry, credentials configuration options (Secrets Manager or direct username/password), and VPC network settings including VPC, subnet, and security group selections.

Set up table and permissions in Amazon Redshift

To set up table and permissions in Amazon Redshift, follow these steps:

  1. On the Amazon Redshift console, choose Query editor v2.
  2. Connect to your existing Redshift cluster.
  3. Create a table with the following DDL. For this post, we create a new database named test and create the following tables in the public schema of test database:
    #Create Database command
    CREATE DATABASE test; 
    
    #Sitemap table creation
    CREATE TABLE public.sitemap(
        path VARCHAR(4096) ENCODE lzo,
        type VARCHAR(255) ENCODE lzo,
        lastSubmitted TIMESTAMP ENCODE delta,
        isPending BOOLEAN NULL ENCODE raw,
        isSitemapsIndex BOOLEAN NULL ENCODE raw,
        lastDownloaded TIMESTAMP NULL ENCODE delta,
        warnings BIGINT NULL ENCODE delta,
        errors BIGINT NULL ENCODE delta,
        contents VARCHAR(65535) NULL ENCODE lzo) DISTSTYLE AUTO;
        
    #Search Analytics table creation
    CREATE TABLE public.search_analytics (
        keys character varying(2048) ENCODE lzo,
        clicks double precision ENCODE raw,
        impressions double precision ENCODE raw,
        ctr numeric(38, 18) ENCODE az64,
        position double precision ENCODE raw
    ) DISTSTYLE AUTO;
    
    #Sites table creation
     CREATE TABLE public.sites (
        siteurl character varying(2048) ENCODE lzo,
        permissionLevel character varying(50) ENCODE lzo
    ) DISTSTYLE AUTO;

    Screenshot of AWS Glue ETL job visual editor showing the job creation interface with source and target selection options, displaying Google Search Console as source and Amazon Redshift as target.

Create ETL job in AWS Glue

To create a data flow in AWS Glue, follow these steps:

  1. On the AWS Glue console, choose ETL jobs in the navigation pane.
  2. Choose Visual ETL under Create job.
    Each ETL job in AWS Glue is priced based on its duration.

    Screenshot of AWS Glue visual ETL canvas showing a data flow diagram with Google Search Console source node connected to Amazon Redshift target node.

  3. For the source, choose Google Search Console, and for the target, choose Amazon Redshift.
    Screenshot of AWS Glue source node configuration panel showing Google Search Console connection settings with entity selection (Sites) and field selection options (siteUrl and permissionLevel).
  4. Choose Source (Google Search Console) to configure the properties, which opens in the right window pane.
  5. Choose the Google Search Console connection created in the previous sections, and provide the entity name. At the time of writing, there are three supported entities: Search Analytics, Sites, and Sitemaps, with multiple supported fields and operators for each entity. Choose the entity name and the corresponding fields; by default, the connector selects all fields. The example shows selecting the entity Site and corresponding fields siteUrl and permissionLevel.
    Screenshot of AWS Glue target node configuration panel showing Amazon Redshift connection settings including schema selection, table name, data handling method (Append to target table), and S3 staging directory configuration.
  6. Choose Target (Amazon Redshift) to configure the properties, which opens in the right pane.
  7. Choose the Amazon Redshift connection, schema, and table name that were created in the previous steps. In this example, we use Append to target table as the method for handling the data. An S3 directory is provided for staging temporary data.
    Screenshot of AWS Glue target node configuration panel showing Amazon Redshift connection settings including schema selection, table name, data handling method (Append to target table), and S3 staging directory configuration.
  8. Navigate to Job details and provide a job name and IAM role (which the job will assume while running). This is the same role created earlier.
  9. Choose Save and Run. For this example, we use AWS Glue version 5.0, keeping all other configuration values under Job details at their defaults. For this example, we have not implemented any schema mapping, so the columns in Amazon Redshift were created to match the output response for the Search entity.
  10. After the job has completed successfully, navigate to Query Editor v2 in Amazon Redshift and query the Sites table to preview the data.
    Screenshot of Amazon Redshift Query Editor v2 showing query results from the Sites table with columns for siteurl and permissionlevel, displaying sample data rows.Screenshot of Amazon Redshift Query Editor v2 showing query results from the Sites table with columns for siteurl and permissionlevel, displaying sample data rows.
  11. In the case of job failures, validate the connections by doing a data preview, and refer to Troubleshooting AWS Glue.
  12. Similar to the Site entity, you can load Sitemap entity data by changing the source properties and destination table in the target Redshift cluster, then choosing Run.
    Screenshot of AWS Glue source node configuration showing Google Search Console entity selection changed to Sitemaps with corresponding fields selected.
  13. Navigate to Query Editor v2 in Amazon Redshift and query the sitemap table to preview the data.
    Screenshot of Amazon Redshift Query Editor v2 showing query results from the sitemap table with columns including path, type, lastsubmitted, ispending, issitemapsindex, lastdownloaded, warnings, errors, and contents.
  14. Similar to Sitemap, you can load Search Analytics entity data by changing the source properties and destination table in the target Redshift cluster, then choosing Run.
    Screenshot of AWS Glue source node configuration showing Google Search Console entity selection changed to Search Analytics with corresponding fields selected.
  15. Navigate to Query Editor v2 in Amazon Redshift and query the search_analytics table and preview the data.
    Screenshot of Amazon Redshift Query Editor v2 showing query results from the search_analytics table with columns for keys, clicks, impressions, ctr, and position.

Filter predicates with Search Analytics

The Search Analytics entity provides support for multiple filters that can be used to view the traffic data for the sites. The following examples show use of some filter predicates you can use that Google Search Console connections support.

  • start_end_date – The default value for start_end_date is between <30 days ago from the current date> AND <yesterday>. To use a different date range, use the between The following example displays search data from January through September 2025:
    start_end_date between '2025-01-01' AND '2025-09-30'

    Screenshot of AWS Glue source node configuration showing Search Analytics entity with a filter predicate for start_end_date between '2025-01-01' AND '2025-09-30'.

  • device – The device filters result against specified device type like DESKOP, MOBILE, and TABLET:
    device = 'MOBILE'

    Screenshot of AWS Glue source node configuration showing Search Analytics entity with a filter predicate for device = 'MOBILE'.

  • country – You can filter against the specified country, as specified by three-letter country code (ISO 3166-1 alpha-3):
    dimensions='country'

    Screenshot of AWS Glue source node configuration showing Search Analytics entity with dimensions set to 'country'.

  • dimensions: Dimensions help group zero or more results for filtering search data by country or device. The following example displays search data grouped by country, and also grouping by country and filtering for mobile devices:
    dimensions='country' AND country='ind' AND device ='MOBILE'

    Screenshot of AWS Glue source node configuration showing Search Analytics entity with multiple filter predicates including dimensions='country', country='ind', and device='MOBILE'.

Run analytical queries on Amazon Redshift

In this section, we run analytical queries using aggregated data across different search entities.

List all countries where site position is less than 10 and device type is MOBILE:

SELECT * from search_analytics_device_country where position < 10 AND keys LIKE '%MOBILE%'

Screenshot of Amazon Redshift Query Editor v2 showing query results for countries where site position is less than 10 and device type is MOBILE, displaying data from the search_analytics_device_country table.

List all countries where impressions are greater than 1 and position is less than 10:

SELECT * FROM "test"."public"."search_analytics_country" where impressions > 1 and position < 10;

Screenshot of Amazon Redshift Query Editor v2 showing query results for countries where impressions are greater than 1 and position is less than 10, displaying data from the search_analytics_country table.

Clean up

To avoid incurring charges, clean up the resources in your AWS account by completing the following steps:

  1. On the AWS Glue console, in the navigation pane, choose Job monitoring.
  2. Stop any running jobs created for Google Search Console connections.
  3. From the list of connections, select the connection name created and delete it.
  4. Delete the Redshift provisioned cluster or the Redshift Serverless workspace and namespace. Amazon Redshift pricing is applied during the cluster’s runtime based on cluster configuration.
  5. Clean up resources in your Google account by deleting the project that contains the Google Project resources. For instructions, refer to Delete your project.

Conclusion

In this post, we walked you through the process of using AWS Glue to integrate data from Google Search Console and write it to Amazon Redshift, a petabyte-scale data warehouse. Whether you’re archiving historical data, performing complex analytics, or preparing data for machine learning, this connector streamlines the process and helps create an integrated data pipeline.

For more information, refer to AWS Glue support for Google Search Console.


About the authors

Anirudh Chawla

Anirudh Chawla

Anirudh is an AWS Analytics Specialist Solutions Architect. He likes to read books, take long walks in nature, and participate in community programs.

Shubham Purwar

Shubham Purwar

Shubham is an AWS Analytics Specialist Solution Architect. In his free time, Shubham loves to spend time with his family and travel around the world.

Shaswat Mandhanya

Shaswat Mandhanya

Shaswat is an AWS Analytics Specialist BD. In his free time, he likes to watch Formula 1 races and travel across the country.

Prabhu G

Prabhu G

Prabhu is a Solutions Architect at AWS. He is an avid supporter of Chennai Super Kings and a big-time fan of MS Dhoni.

Orchestrate end-to-end scalable ETL pipeline with Amazon SageMaker workflows

Post Syndicated from Shubham Kumar original https://aws.amazon.com/blogs/big-data/orchestrate-end-to-end-scalable-etl-pipeline-with-amazon-sagemaker-workflows/

Amazon SageMaker Unified Studio serves as a collaborative workspace where data engineers and scientists can work together on end-to-end data and machine learning (ML) workflows. SageMaker Unified Studio specializes in orchestrating complex data workflows across multiple AWS services through its integration with Amazon Managed Workflows for Apache Airflow (Amazon MWAA). Project owners can create shared environments where team members jointly develop and deploy workflows, while maintaining oversight of pipeline execution. This unified approach makes sure data pipelines run consistently and efficiently, with clear visibility into the entire process, making it seamless for teams to collaborate on sophisticated data and ML projects.

This post explores how to build and manage a comprehensive extract, transform, and load (ETL) pipeline using SageMaker Unified Studio workflows through a code-based approach. We demonstrate how to use a single, integrated interface to handle all aspects of data processing, from preparation to orchestration, by using AWS services including Amazon EMR, AWS Glue, Amazon Redshift, and Amazon MWAA. This solution streamlines the data pipeline through a single UI.

Example use case: Customer behavior analysis for an ecommerce platform

Let’s consider a real-world scenario: An e-commerce company wants to analyze customer transactions data to create a customer summary report. They have data coming from multiple sources:

  • Customer profile data stored in CSV files
  • Transaction history in JSON format
  • Website clickstream data in semi-structured log files

The company wants to do the following:

  • Extract data from these sources
  • Clean and transform the data
  • Perform quality checks
  • Load the processed data into a data warehouse
  • Schedule this pipeline to run daily

Solution overview

The following diagram illustrates the architecture that you implement in this post.

This architecture diagram illustrates a comprehensive, end-to-end data processing pipeline built on AWS services, orchestrated through Amazon SageMaker Unified Studio. The pipeline demonstrates best practices for data ingestion, transformation, quality validation, advanced processing, and analytics.

The workflow consists of the following steps:

  1. Establish a data repository by creating an Amazon Simple Storage Service (Amazon S3) bucket with an organized folder structure for customer data, transaction history, and clickstream logs, and configure access policies for seamless integration with SageMaker Unified Studio.
  2. Extract data from the S3 bucket using AWS Glue jobs.
  3. Use AWS Glue and Amazon EMR Serverless to clean and transform the data.
  4. Implement data quality validation using AWS Glue Data Quality.
  5. Load the processed data into Amazon Redshift Serverless.
  6. Create and manage the workflow environment using SageMaker Unified Studio with Identity Center–based domains.

Note: Amazon SageMaker Unified Studio supports two domain configuration models: IAM Identity Center (IdC)–based domains and IAM role–based domains. While IAM-based domains enable role-driven access management and visual workflows, this post specifically focuses on Identity Center–based domains, where users authenticate via IdC and projects access data and resources using project roles and identity-based authorization.

Prerequisites

Before beginning, ensure you have the following resources:

Configure Amazon SageMaker Unified Studio domain

This solution requires SageMaker Unified Studio domain in the us-east-1 AWS Region. Although SageMaker Unified Studio is available in multiple Regions, this post uses us-east-1 for consistency. For a complete list of supported Regions, refer to Regions where Amazon SageMaker Unified Studio is supported.

Complete the following steps to configure your domain:

  1. Sign in to the AWS Management Console, navigate to Amazon SageMaker, and open the Domains section from the left navigation pane.
  2. On the SageMaker console, choose Create domain, then choose Quick setup.
  3. If the message “No VPC has been specifically set up for use with Amazon SageMaker Unified Studio” appears, select Create VPC. The process redirects to an AWS CloudFormation stack. Leave all settings at their default values and select Create stack.
  4. Under Quick setup settings, for Name, enter a domain name (for example, etl-ecommerce-blog-demo). Review the selected configurations.
  5. Choose Continue to proceed.
  6. On the Create IAM Identity Center user page, create an SSO user (account with IAM Identity Center) or select an existing SSO user to log in to the Amazon SageMaker Unified Studio. The SSO selected here is used as the administrator in the Amazon SageMaker Unified Studio.
  7. Choose Create domain.

For detailed instructions, see Create a SageMaker domain and Onboarding data in Amazon SageMaker Unified Studio.

# Amazon SageMaker Domain Details Interface This screenshot shows the Amazon SageMaker domain details page for "etl-ecommerce-blog-demo

After you have created a domain, popup will appear with the message: “Your domain has been created! You can now log in to Amazon SageMaker Unified Studio”. You can close the popup for now.

Create a project

In this section, we create a project to serve as a collaborative workspace for teams to work on business use cases. Complete the following steps:

  1. Choose Open Unified Studio and sign in with your SSO credentials using the Sign in with SSO option.
  2. Choose Create project.
  3. Name the project (for example, ETL-Pipeline-Demo) and create it using the All capabilities project profile.
  4. Choose Continue.
  5. Keep the default values for the configuration parameters and choose Continue.
  6. Choose Create project.

Project creation might take a few minutes. After the project is created, the environment will be configured for data access and processing.

Integrate S3 bucket with SageMaker Unified Studio

To enable external data processing within SageMaker Unified Studio, configure integration with an S3 bucket. This section walks through the steps to set up the S3 bucket, configure permissions, and integrate it with the project.

Create and configure S3 bucket

Complete the following steps to create your bucket:

  1. In a new browser tab, open the AWS Management Console and search for S3.
  2. On the Amazon S3 console, choose Create Bucket .
  3. Create a bucket named ecommerce-raw-layer-bucket-demo-<Account-ID>-us-east-1. For detailed instructions, see create a general-purpose Amazon S3 bucket for storage.
  4. Create the following folder structure in the bucket. For detailed instructions, see Creating a folder:
    • raw/customers/
    • raw/transactions/
    • raw/clickstream/
    • processed/
    • analytics/

Upload sample data

In this section, we upload sample ecommerce data that represents a typical business scenario where customer behavior, transaction history, and website interactions need to be analyzed together.

The raw/customers/customers.csv file contains customer profile information, including registration details. This structured data will be processed first to establish the customer dimension for our analytics.
customer_id,name,email,registration_date
1,John Doe,[email protected],2022-01-15
2,Jane Smith,[email protected],2022-02-20
3,Robert Johnson,[email protected],2022-01-30
4,Emily Brown,[email protected],2022-03-05
5,Michael Wilson,[email protected],2022-02-10

The raw/transactions/transactions.json file contains purchase transactions with nested product arrays. This semi-structured data will be flattened and joined with customer data to analyze purchasing patterns and customer lifetime value.
[
{"transaction_id": "t1001", "customer_id": 1, "amount": 125.99, "date": "2023-01-10", "items": ["product1", "product2"]},
{"transaction_id": "t1002", "customer_id": 2, "amount": 89.50, "date": "2023-01-12", "items": ["product3"]},
{"transaction_id": "t1003", "customer_id": 1, "amount": 45.25, "date": "2023-01-15", "items": ["product2"]},
{"transaction_id": "t1004", "customer_id": 3, "amount": 210.75, "date": "2023-01-18", "items": ["product1", "product4", "product5"]},
{"transaction_id": "t1005", "customer_id": 4, "amount": 55.00, "date": "2023-01-20", "items": ["product3", "product6"]}
]

The raw/clickstream/clickstream.csv file captures user website interactions and behavior patterns. This time-series data will be processed to understand customer journey and conversion funnel analytics.
timestamp,customer_id,page,action
2023-01-10T10:15:23,1,homepage,view
2023-01-10T10:16:45,1,product_page,view
2023-01-10T10:18:12,1,product_page,add_to_cart
2023-01-10T10:20:30,1,checkout,view
2023-01-10T10:22:15,1,checkout,purchase
2023-01-12T14:30:10,2,homepage,view
2023-01-12T14:32:20,2,product_page,view
2023-01-12T14:35:45,2,product_page,add_to_cart
2023-01-12T14:40:12,2,checkout,view
2023-01-12T14:42:30,2,checkout,purchase

raw

For detailed instructions on uploading files to Amazon S3, refer to the Uploading objects.

Configure CORS policy

To allow access from the SageMaker Unified Studio domain portal, update the Cross-Origin Resource Sharing (CORS) configuration of the bucket:

  1. On the bucket’s Permissions tab, choose Edit under Cross-origin resource sharing (CORS).
    permission
  2. Enter the following CORS policy and replace domainUrl with the SageMaker Unified Studio domain URL (for example, https://<domain-id>.sagemaker.us-east-1.on.aws ). The URL can be found at the top of the domain details page on the SageMaker Unified Studio console.
    [
        {
            "AllowedHeaders": [
                "*"
            ],
            "AllowedMethods": [
                "PUT",
                "GET",
                "POST",
                "DELETE",
                "HEAD"
            ],
            "AllowedOrigins": [
                "domainUrl"
            ],
            "ExposeHeaders": [
                "x-amz-version-id"
            ]
        }
    ]

For detailed information, see Adding Amazon S3 data and gain access using the project role.

Grant Amazon S3 access to SageMaker project role
To enable SageMaker Unified Studio to access the external Amazon S3 location, the corresponding AWS Identity and Access Management (IAM) project role must be updated with the required permissions. Complete the following steps:
  1. On the IAM console, choose Roles in the navigation pane.
  2. Search for the project role using the last segment of the project role Amazon Resource Name (ARN). This information is located on the Project overview page in SageMaker Unified Studio (for example, datazone_usr_role_1a2b3c45de6789_abcd1efghij2kl).
    project detail
  3. Choose the project role to open the role details page.
  4. On the Permissions tab, choose Add permissions, then choose Create inline policy.
  5. Use the JSON editor to create a policy that grants the project role access to the Amazon S3 location
  6. In the JSON policy below, replace the placeholder values with your actual environment details:
    • Replace <BUCKET_PREFIX> with the prefix of S3 bucket name (for example, ecommerce-raw-layer)
    • Replace <AWS_REGION> with the AWS Region where your AWS Glue Data Quality rulesets are created (for example, us-east-1)
    • Replace <AWS_ACCOUNT_ID> with your AWS account ID
  7. Paste the updated JSON policy into the JSON editor.
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "ETLBucketListAccess",
                "Effect": "Allow",
                "Action": [
                    "s3:ListBucket",
                    "s3:GetBucketLocation"
                ],
                "Resource": "arn:aws:s3:::<BUCKET_PREFIX>-*"
            },
            {
                "Sid": "ETLObjectAccess",
                "Effect": "Allow",
                "Action": [
                    "s3:GetObject",
                    "s3:PutObject",
                    "s3:DeleteObject"
                ],
                "Resource": "arn:aws:s3:::<BUCKET_PREFIX>-*/*"
            },
            {
                "Sid": "GlueDataQualityPublish",
                "Effect": "Allow",
                "Action": [
                    "glue:PublishDataQuality"
                ],
     "Resource":"arn:aws:glue:<AWS_REGION>:<AWS_ACCOUNT_ID>:dataQualityRuleset/*"
            }
        ]
    }

  8. Choose Next.
  9. Enter a name for the policy (for example, etl-rawlayer-access), then choose Create policy.
  10. Choose Add permissions again, then choose Create inline policy.
  11. In the JSON editor, create a second policy to manage S3 Access Grants:Replace <BUCKET_PREFIX> with the prefix of S3 bucket name (for example, ecommerce-raw-layer) and paste this JSON policy.
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "S3AGLocationManagement",
                "Effect": "Allow",
                "Action": [
                    "s3:CreateAccessGrantsLocation",
                    "s3:DeleteAccessGrantsLocation",
                    "s3:GetAccessGrantsLocation"
                ],
                "Resource": [
                    "arn:aws:s3:*:*:access-grants/default/*"
                ],
                "Condition": {
                    "StringLike": {
                        "s3:accessGrantsLocationScope": "s3://<BUCKET_PREFIX>-*/*"
                    }
                }
            },
            {
                "Sid": "S3AGPermissionManagement",
                "Effect": "Allow",
                "Action": [
                    "s3:CreateAccessGrant",
                    "s3:DeleteAccessGrant"
                ],
                "Resource": [
                    "arn:aws:s3:*:*:access-grants/default/location/*",
                    "arn:aws:s3:*:*:access-grants/default/grant/*"
                ],
                "Condition": {
                    "StringLike": {
                        "s3:accessGrantScope": "s3://<BUCKET_PREFIX>-*/*"
                    }
                }
            }
        ]
    }

  12. Choose Next.
  13. Enter a name for the policy (for example, s3-access-grants-policy), then choose Create policy.

create policy

For detailed information about S3 Access Grants, see Adding Amazon S3 data.

Add S3 bucket to project

After you add policies to the project role for access to the Amazon S3 resources, complete the following steps to integrate the S3 bucket with the SageMaker Unified Studio project:

  1. In SageMaker Unified Studio, open the project you created under Your projects.
    your projects
  2. Choose Data in the navigation pane.
  3. Select Add and then Add S3 location.
    add s3
  4. Configure the S3 location:
    1. For Name, enter a descriptive name (for example, E-commerce_Raw_Data).
    2. For S3 URI, enter your bucket URI (for example, s3://ecommerce-raw-layer-bucket-demo-<Account-ID>-us-east-1/).
    3. For AWS Region, enter your Region (for this example, us-east-1).
    4. Leave Access role ARN blank.
    5. Click Add S3 Location
  5. Wait for the integration to complete.
  6. Verify the S3 location appears in your project’s data catalog (on the Project overview page, on the Data tab, locate the Buckets pane to view the buckets and folders).

add

This process connects your S3 bucket to SageMaker Unified Studio, making your data ready for analysis.

Create notebook for job scripts

Before you can create the data processing jobs, you must set up a notebook to develop the scripts that will generate and process your data. Complete the following steps:

  1. In SageMaker Unified Studio, on the top menu, under Build, choose JupyterLab.
  2. Choose Configure Space and choose the instance type ml.t3.xlarge. This makes sure your JupyterLab instance has at least 4 vCPUs and 4 GiB of memory.
  3. Choose Configure and Start Space or Save and Restart to launch your environment.
  4. Wait a few moments for the instance to be ready.
  5. Choose File, New, and Notebook to create a new notebook.
  6. Set Kernel as Python 3, Connection type as PySpark, and Compute as Project.spark.compatibility.
    jupyter
  7. In the notebook, enter the following script to use later for your AWS Glue job. This script processes raw data from three sources in the S3 data lake, standardizes dates, and converts data types before saving the cleaned data in Parquet format for optimal storage and querying.
  8. Replace <Bucket-Name> with the name of actual S3 bucket in script:
    import sys
    from awsglue.transforms import *
    from pyspark.context import SparkContext
    from awsglue.context import GlueContext
    from awsglue.job import Job
    from awsglue.utils import getResolvedOptions
    from pyspark.sql import functions as F
    args = getResolvedOptions(sys.argv, ['JOB_NAME'])
    sc = SparkContext.getOrCreate()
    glueContext = GlueContext(sc)
    spark = glueContext.spark_session
    job = Job(glueContext)
    job.init(args['JOB_NAME'], args)
    # Customers
    customer_df = (
        spark.read
        .option("header", "true")
        .csv("s3://<Bucket-Name>/raw/customers/")
        .withColumn("registration_date", F.to_date("registration_date"))
        .withColumn("processed_at", F.current_timestamp())
    )
    customer_df.write.mode("overwrite").parquet(
        "s3://<Bucket-Name>/processed/customers/"
    )
    # Transactions
    transaction_df = (
        spark.read
        .json("s3://<Bucket-Name>/raw/transactions/")
        .withColumn("date", F.to_date("date"))
        .withColumn("customer_id", F.col("customer_id").cast("int"))
        .withColumn("processed_at", F.current_timestamp())
    )
    transaction_df.write.mode("overwrite").parquet(
        "s3://<Bucket-Name>/processed/transactions/"
    )
    # Clickstream
    clickstream_df = (
        spark.read
        .option("header", "true")
        .csv("s3://<Bucket-Name>/raw/clickstream/")
        .withColumn("customer_id", F.col("customer_id").cast("int"))
        .withColumn("timestamp", F.to_timestamp("timestamp"))
        .withColumn("processed_at", F.current_timestamp())
    )
    clickstream_df.write.mode("overwrite").parquet(
        "s3://<Bucket-Name>/processed/clickstream/"
    )
    print("Data processing completed successfully")
    job.commit()

    This script processes customer, transaction, and clickstream data from the raw layer in Amazon S3 and saves it as Parquet files in the processed layer.

  9. Choose File, Save Notebook As, and save the file as shared/etl_initial_processing_job.ipynb.
    jupyter2

Create notebook for AWS Glue Data Quality

After you create the initial data processing script, the next step is to set up a notebook to perform data quality checks using AWS Glue. These checks help validate the integrity and completeness of your data before further processing. Complete the following steps:

  1. Choose File, New, and Notebook to create a new notebook.
  2. Set Kernel as Python 3, Connection type as PySpark, and Compute as Project.spark.compatibility.
    select-kernel
  3. In this new notebook, add the data quality check script using the AWS Glue EvaluateDataQuality method. Replace <Bucket-Name> with the name of actual S3 bucket in script:
    from datetime import datetime
    from pyspark.context import SparkContext
    from awsglue.context import GlueContext
    from awsglue.job import Job
    from awsgluedq.transforms import EvaluateDataQuality
    from awsglue.transforms import SelectFromCollection
    
    # ---------------- Glue setup ----------------
    sc = SparkContext.getOrCreate()
    glueContext = GlueContext(sc)
    job = Job(glueContext)
    job.init("GlueDQJob", {})
    
    # ---------------- Constants ----------------
    RUN_DATE = datetime.utcnow().strftime("%Y-%m-%d")
    year, month, day = RUN_DATE.split("-")
    OUTPUT_PATH = "s3://<Bucket-Name>/data-quality-results"
    
    # ---------------- Tables and Rules ----------------
    tables = {
        "customers": ["s3://<Bucket-Name>/processed/customers/",
                      ["IsComplete \"customer_id\"", "IsUnique \"customer_id\"", "IsComplete \"email\""]],
        "transactions": ["s3://<Bucket-Name>/processed/transactions/",
                         ["IsComplete \"transaction_id\"", "IsUnique \"transaction_id\""]],
        "clickstream": ["s3://<Bucket-Name>/processed/clickstream/",
                        ["IsComplete \"customer_id\"", "IsComplete \"action\""]]
    }
    
    # ---------------- Process Each Table ----------------
    for table, (path, rules) in tables.items():
        df = glueContext.create_dynamic_frame.from_options("s3", {"paths":[path]}, "parquet")
        results = EvaluateDataQuality().process_rows(
            frame=df,
            ruleset=f"Rules = [{', '.join(rules)}]",
            publishing_options={"dataQualityEvaluationContext": table}
        )
        rows = SelectFromCollection.apply(results, key="rowLevelOutcomes", transformation_ctx="rows").toDF()
        rows = rows.drop("DataQualityRulesPass", "DataQualityRulesFail", "DataQualityRulesSkip")
    
        # Write passed/failed rows
        for status, colval in [("pass","Passed"), ("fail","Failed")]:
            tmp = rows.filter(rows.DataQualityEvaluationResult.contains(colval))
            if tmp.count() > 0:
                tmp.write.mode("append").parquet(
            f"{OUTPUT_PATH}/{table}/status=dq_{status}/Year={year}/Month={month}/Date={day}"
                )
    print("Data Quality checks completed and written to S3")
    job.commit()

  4. Choose File, Save Notebook As, and save the file as shared/etl_data_quality_job.ipynb.
Create and test AWS Glue jobs

Jobs in SageMaker Unified Studio enable scalable, flexible ETL pipelines using AWS Glue. This section walks through creating and testing data processing jobs for efficient and governed data transformation.
Create initial data processing job

This job performs the first processing job in the ETL pipeline, transforming raw customer, transaction, and clickstream data and writing the cleaned output to Amazon S3 in Parquet format. Complete the following steps to create the job:

  1. In SageMaker Unified Studio, go to your project.
  2. On the top menu, choose Build, and under Data Analysis & Integration, choose Data processing jobs.
    navbar on smus
  3. Choose Create job from notebooks.
  4. Under Choose project files, choose Browse files.
  5. Locate and select etl_initial_processing_job.ipynb (the notebook saved earlier in JupyterLab), then choose Select and Next.
    select the notebook
  6. Configure the job settings:
    1. For Name, enter a name (for example, job-1).
    2. For Description, enter a description (for example, Initial ETL job for customer data processing).
    3. For IAM Role, choose the project role (default).
    4. For Type, choose Spark.
    5. For AWS Glue version, use version 5.0.
    6. For Language, choose Python.
    7. For Worker type, use G.1X.
    8. For Number of Instances, set to 10.
    9. For Number of retries, set to 0.
    10. For Job timeout, set to 480.
    11. For Compute connection, choose project.spark.compatibility.
    12. Under Advanced settings, turn on Continuous logging.

    advanced setting

  7. Leave the remaining settings as default, then choose Submit.

After the job is created, a confirmation message will appear indicating that job-1 was created successfully.

Create AWS Glue Data Quality job

This job runs data quality checks on the transformed datasets using AWS Glue Data Quality. Rulesets validate completeness and uniqueness for key fields. Complete the following steps to create the job:

  1. In SageMaker Unified Studio, go to your project.
  2. On the top menu, choose Build, and under Data Analysis & Integration, choose Data processing jobs.
  3. Choose Create job, Code-based job, and Create job from files.
  4. Under Choose project files, choose Browse files.
  5. Locate and select etl_glue_data_quality.ipynb, then choose Select and Next.
  6. Configure the job settings:
  7. For Name, enter a name (for example, job-2).
  8. For Description, enter a description (for example, Data quality checks using AWS Glue Data Quality).
  9. For IAM Role, choose the project role.
  10. For Type, choose Spark.
  11. For AWS Glue version, use version 5.0.
  12. For Language, choose Python.
  13. For Worker type, use G.1X.
  14. For Number of Instances, set to 10.
  15. For Number of retries, set to 0.
  16. For Job timeout, set to 480.
  17. For Compute connection, choose project.spark.compatibility.
  18. Under Advanced settings, turn on Continuous logging.
  19. Leave the remaining settings as default, then choose Submit.

After the job is created, a confirmation message will appear indicating that job-2 was created successfully.

Test AWS Glue jobs

Test both jobs to make sure they execute successfully:

  1. In SageMaker Unified Studio, go to your project.
  2. On the top menu, choose Build, and under Data Analysis & Integration, choose Data processing jobs.
  3. Select job-1 and choose Run job.
  4. Monitor the job execution and verify it completes successfully.
  5. Similarly, select job-2 and choose Run job.
  6. Monitor the job execution and verify it completes successfully.

Add EMR Serverless compute

In the ETL pipeline, we use EMR Serverless to perform compute-intensive transformations and aggregations on large datasets. It automatically scales resources based on workload, offering high performance with simplified operations. By integrating EMR Serverless with SageMaker Unified Studio, you can simplify the process of running Spark jobs interactively using Jupyter notebooks in a serverless environment.

This section walks through the steps to configure EMR Serverless compute within SageMaker Studio and use it for executing distributed data processing jobs.

Configure EMR Serverless in SageMaker Unified Studio

To use EMR Serverless for processing in the project, follow these steps:

  1. In the navigation pane on Project Overview, choose Compute.
  2. On the Data processing tab, choose Add compute and Create new compute resources.
  3. Select EMR Serverless and choose Next.
  4. Configure EMR Serverless settings:
  5. For Compute name, enter a name (for example, etl-emr-serverless).
  6. For Description, enter a description (for example, EMR Serverless for advanced data processing).
  7. For Release label, choose emr-7.8.0.
  8. For Permission mode, choose Compatibility.
  9. Choose Add Compute to complete the setup.

After it’s configured, the EMR Serverless compute will be listed with the deployment status Active.

emr serverless

Create and run notebook with EMR Serverless

After you create the EMR Serverless compute, you can run PySpark-based data transformation jobs using a Jupyter notebook to perform large-scale data transformations. This job reads cleaned customer, transaction, and clickstream datasets from Amazon S3, performs aggregations and scoring, and writes the final analytics outputs back to Amazon S3 in both Parquet and CSV formats.Complete the following steps to create a notebook for EMR Serverless processing:

  1. On the top menu, under Build, choose JupyterLab.
  2. Choose File, New, and Notebook.
  3. Set Kernel as Python 3, Connection type as PySpark, and Compute as emr-s.etl-emr-serverless.
    compute
  4. Enter the following PySpark script to run your data transformation job on EMR Serverless. Provide the name of your S3 bucket:
    from pyspark.sql import SparkSession
    from pyspark.sql import functions as F
    
    spark = SparkSession.builder.appName("CustomerAnalytics").getOrCreate()
    
    customers = spark.read.parquet("s3://<bucket-name>/processed/customers/")
    transactions = spark.read.parquet("s3://<bucket-name>/processed/transactions/")
    clickstream = spark.read.parquet("s3://<bucket-name>/processed/clickstream/")
    
    customer_spending = transactions.groupBy("customer_id").agg(
        F.count("transaction_id").alias("total_transactions"),
        F.sum("amount").alias("total_spent"),
        F.avg("amount").alias("avg_transaction_value"),
        F.datediff(F.current_date(), F.max("date")).alias("days_since_last_purchase")
    )
    
    customer_engagement = clickstream.groupBy("customer_id").agg(
        F.count("*").alias("total_clicks"),
        F.countDistinct("page").alias("unique_pages_visited"),
        F.count(F.when(F.col("action") == "purchase", 1)).alias("purchase_actions"),
        F.count(F.when(F.col("action") == "add_to_cart", 1)).alias("add_to_cart_actions")
    )
    
    customer_analytics = customers.join(customer_spending, on="customer_id", how="left").join(
        customer_engagement, on="customer_id", how="left")
    
    customer_analytics = customer_analytics.na.fill(0, [
        "total_transactions", "total_spent", "total_clicks", 
        "unique_pages_visited", "purchase_actions", "add_to_cart_actions"
    ])
    
    customer_analytics = customer_analytics.withColumn(
        "customer_value_score",
        (F.col("total_spent") * 0.5) + (F.col("total_transactions") * 0.3) + (F.col("purchase_actions") * 0.2)
    )
    
    customer_analytics.write.mode("overwrite").parquet("s3://<bucket-name>/analytics/customer_analytics/")
    
    customer_summary = customer_analytics.select(
        "customer_id", "name", "email", "registration_date", 
        "total_transactions", "total_spent", "avg_transaction_value",
        "days_since_last_purchase", "total_clicks", "purchase_actions",
        "customer_value_score"
    )
    
    customer_summary.write.mode("overwrite").option("header", "true").csv("s3://<bucket-name>/analytics/customer_summary/")
    
    print("EMR processing completed successfully")

  5. Choose File, Save Notebook As, and save the file as shared/emr_data_transformation_job.ipynb.
  6. Choose Run Cell to run the script.
  7. Monitor the Script execution and verify it completes successfully.
  8. Monitor the Spark job execution and ensure it completes without errors.

emr run

Add Redshift Serverless compute

With Redshift Serverless, users can run and scale data warehouse workloads without managing infrastructure. It is ideal for analytics use cases where data needs to be queried from Amazon S3 or integrated into a centralized warehouse. In this step, you add Redshift Serverless to the project for loading and querying processed customer analytics data generated in earlier stages of the pipeline. For more information about Redshift Serverless, see Amazon Redshift Serverless.

Set up Redshift Serverless compute in SageMaker Unified Studio

Complete the following steps to set up Redshift Serverless compute:

  1. In SageMaker Unified Studio, choose the Compute tab within your project workspace (ETL-Pipeline-Demo).
  2. On the SQL analytics tab, choose Add compute, then choose Create new compute resources to begin configuring your compute environment.
  3. Select Amazon Redshift Serverless.
  4. Configure the following:
    1. For Compute name, enter a name (for example, ecommerce_data_warehouse).
    2. For Description, enter a description (for example, Redshift Serverless for data warehouse).
    3. For Workgroup name, enter a name (for example, redshift-serverless-workgroup).
    4. For Maximum capacity, set to 512 RPUs.
    5. For Database name, enter dev.
  5. Choose Add Compute to create the Redshift Serverless resource.
    Redshift

After the compute is created, you can test the Amazon Redshift connection.

  1. On the Data warehouse tab, confirm that redshift.ecommerce_data_warehouse is listed.
    compute-redshift
  2. Choose the compute: redshift.ecommerce_data_warehouse.
  3. On the Permissions tab, copy the IAM role ARN. You use this for the Redshift COPY command in the next step.
    iam-role

Create and execute querybook to load data into Amazon Redshift

In this step, you create a SQL script to load the processed customer summary data from Amazon S3 into a Redshift table. This enables centralized analytics for customer segmentation, lifetime value calculations, and marketing campaigns. Complete the following steps:

  1. On the Build menu, under Data Analysis & Integration, choose Query editor.
  2. Enter the following SQL into the querybook to create the customer_summary table in the public schema:
    -- Create customer_summary table in public schema
    CREATE TABLE IF NOT EXISTS public.customer_summary (
        customer_id INT PRIMARY KEY,
        name VARCHAR(100),
        email VARCHAR(100),
        registration_date DATE,
        total_transactions INT,
        total_spent DECIMAL(10, 2),
        avg_transaction_value DECIMAL(10, 2),
        days_since_last_purchase INT,
        total_clicks INT,
        purchase_actions INT,
        customer_value_score DECIMAL(10, 2)
    );

  3. Choose Add SQL to add a new SQL script.
  4. Enter the following SQL into the querybook
    TRUNCATE TABLE customer_summary;

    Note: We truncate the customer_summary table to remove existing records and ensure a clean, duplicate-free reload of the latest aggregated data from S3 before running the COPY command.

  5. Choose Add SQL to add a new SQL script.
  6. Enter the following SQL to load the data into Redshift Serverless from your S3 bucket. Provide the name of your S3 bucket and IAM role ARN for Amazon Redshift:
    -- Load data from S3 (replace with your bucket name and IAM role)
    COPY public.customer_summary FROM 's3://<bucket-name>/analytics/customer_summary/'
    IAM_ROLE 'arn:aws:iam::<Account-ID>:role/<your-redshift-role>'
    FORMAT AS CSV
    IGNOREHEADER 1
    REGION 'us-east-1';

  7. In the Query Editor, configure the following:
    1. Connection: redshift.ecommerce_data_warehouse
    2. Database: dev
    3. Schema: public

    query

  8. Choose Choose to apply the connection settings.
  9. Choose Run Cell for each cell to create the customer_summary table in the public schema and then load data from Amazon S3.
  10. Choose Actions, Save, name the querybook final_data_product, and choose Save changes.

This completes the creation and execution of the Redshift data product using the querybook.

Create and manage the workflow environment

This section describes how to create a shared workflow environment and define a code-based workflow that automates a customer data pipeline using Apache Airflow within SageMaker Unified Studio. Shared environments facilitate collaboration among project members and centralized workflow management.

Create the workflow environment

Workflow environments must be created by project owners. After they’re created, members of the project can sync and use the workflows. Only project owners can update or delete workflow environments. Complete the following steps to create the workflow environment:

  1. Choose Compute for your project.
  2. On the Workflow environments tab, choose Create.
  3. Review the configuration parameters and choose Create workflow environment.
  4. Wait for the environment to be fully provisioned before proceeding It will take around 20 minutes to provision.

workflow

Create the code-based workflow

When the workflow environment is ready, define a code-based ETL pipeline using Airflow. This pipeline automates daily processing tasks across services like AWS Glue, EMR Serverless, and Redshift Serverless.

  1. On the Build menu, under Orchestration, choose Workflows.
  2. Choose Create new workflow, then choose Create workflow in code editor.
  3. Configure Space and choose the instance type ml.t3.xlarge. This ensures your JupyterLab instance has at least 4 vCPUs and 4 GiB of memory.
  4. Choose Configure and Restart Space to launch your environment.

sample_dag

The following script defines a daily scheduled ETL workflow that automates several actions:

  • Initial data transformation using AWS Glue
  • Data quality validation using AWS Glue (EvaluateDataQuality)
  • Advanced data processing with EMR Serverless using a Jupyter notebook
  • Loading transformed results into Redshift Serverless from a querybook
  1. Replace the default DAG template with the following definition, ensuring that job names and input paths match the actual names used in your project:
    from datetime import datetime
    from airflow import DAG
    from airflow.decorators import dag
    from airflow.utils.dates import days_ago
    from airflow.providers.amazon.aws.operators.glue import GlueJobOperator
    from workflows.airflow.providers.amazon.aws.operators.sagemaker_workflows import NotebookOperator
    from sagemaker_studio import Project
    # Get SageMaker Studio project IAM role
    project = Project()
    default_args = {
        'owner': 'data_engineer',
        'depends_on_past': False,
        'email_on_failure': True,
        'email_on_retry': False,
        'retries': 1
    }
    @dag(
        dag_id='customer_etl_pipeline',
        default_args=default_args,
        schedule_interval='@daily',
        start_date=days_ago(1),
        is_paused_upon_creation=False,
        tags=['etl', 'customer-analytics'],
        catchup=False
    )
    def customer_etl_pipeline():
        # Step 1: Initial data transformation using Glue
        initial_transformation = GlueJobOperator(
            task_id='initial_transformation',
            job_name='job-1',
            iam_role_arn=project.iam_role,
        )
        # Step 2: Data quality checks using Glue DQ
        data_quality_check = GlueJobOperator(
            task_id='data_quality_check',
            job_name='job-6',
            iam_role_arn=project.iam_role,
        )
        # Step 3: EMR Serverless notebook processing
        emr_processing = NotebookOperator(
            task_id='emr_processing',
            input_config={
                "input_path": "emr_data_transformation_job.ipynb",
                "input_params": {}
            },
            output_config={"output_formats": ['NOTEBOOK']},
            poll_interval=10,
        )
        # Step 4: Load to Redshift notebook
        redshift_load = NotebookOperator(
            task_id='redshift_load',
            input_config={
                "input_path": "final_data_product.sqlnb",
                "input_params": {}
            },
            output_config={"output_formats": ['NOTEBOOK']},
            poll_interval=10,
        )
        # Task dependencies
        initial_transformation >> data_quality_check >> emr_processing >> redshift_load
    # Instantiate DAG
    customer_etl_dag = customer_etl_pipeline()

  2. Choose File, Save python file, name the file shared/workflows/dags/customer_etl_pipeline.py, and choose Save.

Deploy and run the workflow

Complete the following steps to run the workflow:

  1. On the Build menu, choose Workflows.
  2. Choose the workflow customer_etl_pipeline and choose Run.

scheduled

Running a workflow puts tasks together to orchestrate Amazon SageMaker Unified Studio artifacts. You can view multiple runs for a workflow by navigating to the Workflows page and choosing the name of a workflow from the workflows list table.

To share your workflows with other project members in a workflow environment, refer to Share a code workflow with other project members in an Amazon SageMaker Unified Studio workflow environment.

Monitor and troubleshoot the workflow

After your Airflow workflows are deployed in SageMaker Unified Studio, monitoring becomes essential for maintaining reliable ETL operations. The integrated Amazon MWAA environment provides comprehensive observability into your data pipelines through the familiar Airflow web interface, enhanced with AWS monitoring capabilities. The Amazon MWAA integration with SageMaker Unified Studio offers real-time DAG execution tracking, detailed task logs, and performance metrics to help you quickly identify and resolve pipeline issues. Complete the following steps to monitor the workflow:

  1. On the Build menu, choose Workflows.
  2. Choose the workflow customer_etl_pipeline.
  3. Choose View runs to see all executions.
  4. Choose a specific run to view detailed task status.

workflows-run

For each task, you can view the status (Succeeded, Failed, Running), start and end times, duration, and logs and outputs. The workflow is also visible in the Airflow UI, accessible through the workflow environment, where you can view the DAG graph, monitor task execution in real time, access detailed logs, and view the status.

  1. Go to Workflows and select the workflow named customer_etl_pipeline.
  2. From the Actions menu, choose Open in Airflow UI.

airflow-ui-smus

After the workflow completes successfully, you can query the data product in the query editor.

  • On the Build menu, under Data Analysis & Integration, choose Query editor.
  • Run select * from "dev"."public"."customer_summary"

query-editor

Observe the contents of the customer_summary table, including aggregated customer metrics such as total transactions, total spent, average transaction value, clicks, and customer value scores. This allows verification that the ETL and data quality pipelines loaded and transformed the data correctly.

Clean up

To avoid unnecessary charges, complete the following steps:

  1. Delete a workflow environment.
  2. If you no longer need it, delete the project.
  3. After you delete the project, delete the domain.

Conclusion

This post demonstrated how to build an end-to-end ETL pipeline using SageMaker Unified Studio workflows. We explored the complete development lifecycle, from setting up fundamental AWS infrastructure—including Amazon S3 CORS configuration and IAM permissions—to implementing sophisticated data processing workflows. The solution incorporates AWS Glue for initial data transformation and quality checks, EMR Serverless for advanced processing, and Redshift Serverless for data warehousing, all orchestrated through Airflow DAGs. This approach offers several key benefits: a unified interface that consolidates necessary tools, Python-based workflow flexibility, seamless AWS service integration, collaborative development through Git version control, cost-effective scaling through serverless computing, and comprehensive monitoring tools—all working together to create an efficient and maintainable data pipeline solution.

By using SageMaker Unified Studio workflows, you can accelerate your data pipeline development while maintaining enterprise-grade reliability and scalability. For more information about SageMaker Unified Studio and its capabilities, refer to the Amazon SageMaker Unified Studio documentation.


About the authors

Shubham Kumar

Shubham Kumar

Shubham is an Associate Delivery Consultant at AWS, specializing in big data, data lakes, data governance, as well as search and observability architectures. In his free time, Shubham enjoys traveling, spending quality time with his family, and writing fictional stories.

Shubham Purwar

Shubham Purwar

Shubham is an Analytics Specialist Solution Architect at AWS. In his free time, Shubham loves to spend time with his family and travel around the world.

Nitin Kumar

Nitin Kumar

Nitin is a Cloud Engineer (ETL) at AWS, specialized in AWS Glue. In his free time, he likes to watch movies and spend time with his family.

Enable strategic data quality management with AWS Glue DQDL labels

Post Syndicated from Arun A K original https://aws.amazon.com/blogs/big-data/enable-strategic-data-quality-management-with-aws-glue-dqdl-labels/

Organizations increasingly depend on trusted, high-quality data to drive analytics, regulatory reporting, and operational decision-making. When data quality issues go undetected, they can lead to inaccurate insights, stalled initiatives, and compliance gaps that directly affect business outcomes. As data volumes grow and pipelines become more distributed, maintaining consistent data quality across teams and data domains becomes progressively more challenging.

You can address these challenges with AWS Glue Data Quality by providing automated, rule-based data validation across datasets in the AWS Glue Data Catalog and within AWS Glue ETL pipelines. With the Data Quality Definition Language (DQDL), you can author both straightforward and advanced validation rules to detect data quality issues early in the lifecycle, before they reach downstream applications or analytics environments.

In this post, we highlight the new DQDL labels feature, which enhances how you organize, prioritize, and operationalize your data quality efforts at scale. We show how labels such as business criticality, compliance requirements, team ownership, or data domain can be attached to data quality rules to streamline triage and analysis. You’ll learn how to quickly surface targeted insights (for example, “all high-priority customer data failures owned by marketing” or “GDPR-related issues from our Salesforce ingestion pipeline”) and how DQDL labels can help teams improve accountability and accelerate remediation workflows.

Managing complex data quality rules across teams and use cases

As organizations advance in their data quality programs, a few rules often grow into hundreds or thousands maintained across many teams and business domains. Take the example of AnyCompany, a large retail organization with multiple data teams managing customer, product, and sales data across different business units. These teams run a variety of data quality rules, including weekly customer checks, daily product validations, frequent sales checks, and monthly compliance reviews, with different naming patterns, schedules, and response processes. This creates a fragmented, hard-to-navigate system where teams operate in isolation and data quality practices become inconsistent.

The challenge lies in the volume of rules and the lack of organizational context around them. When dozens of data quality rules pass or fail, teams still lack clarity on ownership, urgency, or business impact. This slows incident response, limits executive insight, and complicates resource planning. To move from technical monitoring to strategic value, organizations need a unified structure that connects data quality rules to teams, domains, and priorities, bringing essential business context to data quality operations.

Metadata-driven rule organization

AWS Glue DQDL labels address organizational challenges because you can attach custom metadata to data quality rules, transforming anonymous validations into contextually rich, business-aware checks. Labels work as key-value pairs attached to individual rules or entire rule sets, and you can organize quality operations around business dimensions such as team ownership, criticality, frequency, and regulatory requirements, as in the case of the AnyCompany example. When a rule fails, you immediately identify what failed, who should respond, how urgent it is, and which business area is affected, whether it’s the marketing department tracking email completeness with daily frequency tags, compliance teams monitoring age verification with regulation labels, or the finance team validating payment data with high-criticality markers.

Labels integrate with existing DQDL syntax without requiring changes to current rule definitions, working consistently across AWS Glue Data Quality execution contexts. The feature’s flexibility supports organizational taxonomies from cost centers and geographic regions to data sensitivity levels and service-level agreement (SLA) requirements with single rules carrying multiple labels simultaneously for sophisticated filtering and analysis. Labels appear in the outputs, including rule outcomes, row-level results, and API responses, so organizational context travels with quality results whether you’re troubleshooting failures, analyzing trends in Amazon Athena, or building executive dashboards in Amazon Quick Sight.

Getting started: Writing your first labeled data quality rules

Let’s walk through creating your first labeled data quality rules using AnyCompany’s customer data scenario. We’ll use their customer demographics dataset, which contains customer information that multiple teams need to validate with different priorities and frequencies.

DQDL labels follow a straightforward key-value pair syntax that integrates naturally with existing rule definitions. The basic syntax supports two approaches: default labels that apply to the rules in a rule set, and rule-specific labels that apply to individual rules. Rule-specific labels can override default labels when using the same key, providing fine-grained control over your labeling strategy.

When implementing DQDL labels, keep the following constraints in mind:

  • Maximum of 10 labels per rule
  • Label keys are limited to 128 characters and can’t be empty
  • Label values are limited to 256 characters and can’t be empty
  • Both keys and values are case-sensitive
  • Rule-specific labels override default labels when using the same key

Using this labeling approach, you can organize and manage data quality rules efficiently across different teams and validation requirements.

Best practices for label naming conventions

Here are some proven labeling strategies that scale across enterprise environments:

  • Establish a complete standardized taxonomy upfront – Define label keys in DefaultLabels with sensible defaults such as regulation=none or sla=24h to provide rules with identical keys for cross-team queries.
  • Use consistent key naming patterns – Establish standard keys such as team, criticality, sla, impact, and regulation across rule sets to maintain query consistency.
  • Implement hierarchical values – Use formats such as team=marketing-analytics to support both broad and specific filtering while keeping key structure consistent.
  • Include operational metadata in defaults – Define labels such as sla, escalation-level, or notification-channel as defaults to drive automated response workflows.
  • Plan for reporting dimensions – Include keys such as cost-center, region, or business-unit in your default taxonomy to support meaningful business analytics.
  • Use standardized value patterns – Establish consistent formats such as criticality=high/medium/low or sla=15m/1h/1d for predictable filtering and sorting.

These are guidelines rather than requirements but following them from the start enables powerful cross-team analytics and reduces future refactoring effort.

Customer data validation hands-on example

This post assumes you’re familiar with AWS Glue Data Quality and ETL operations. Using the following hands-on walkthrough, you’ll learn how to implement DQDL labels for organizational data quality management.

Start by establishing default labels that automatically apply to every rule in the rule set, providing consistent organizational context:

DefaultLabels = ["team"="data-team", "criticality"="medium", "regulation"="none", "sla"="24h", "impact"="medium"]

DefaultLabels provide a foundational taxonomy that automatically propagates across your entire rule set, creating uniformity and reducing configuration overhead. By defining default values at the organizational level, such as team=data-team, criticality=medium, regulation=none, sla=24h, and impact=medium, every rule inherits these standardized attributes without requiring explicit declaration. This inheritance model promotes consistency while maintaining the flexibility individual teams need to address their unique operational contexts.

Individual teams can selectively override inherited defaults to reflect their specific requirements. For example, examine the following complete rule set:

DefaultLabels = ["team"="data-team", "criticality"="medium", "regulation"="none", "sla"="24h", "impact"="medium"]

Rules = [
    IsComplete "c_customer_id" labels=["team"="analytics", "criticality"="high", "sla"="15m", "impact"="high"],
    ColumnValues "c_customer_id" matches "e.*" labels=["team"="analytics", "criticality"="medium", "impact"="low"],
    ColumnLength "c_city" > 6 labels=["team"="marketing", "criticality"="medium", "sla"="4h", "impact"="medium"],
    IsComplete "c_name" labels=["team"="marketing", "sla"="4h"],
    ColumnValues "c_age" >= 21 labels=["team"="compliance", "criticality"="high", "regulation"="age21", "impact"="high"] with threshold > 0.99,
    IsComplete "c_birth_date" labels=["team"="compliance", "criticality"="medium", "regulation"="gdpr", "impact"="medium"],
    IsComplete "c_creditissuer" labels=["team"="finance", "impact"="high"],
    ColumnValues "c_creditcardnumber" > 100000000000 labels=["team"="finance", "criticality"="high", "regulation"="payment", "impact"="high"] with threshold > 0.95
]

Notice how the compliance team changes regulation from 'none' to 'age21' for age verification rules and analytics elevates criticality to 'high' for business-critical checks. Unspecified labels automatically inherit the default values, providing consistency while maintaining team-level flexibility.

Applying labeled rules against the dataset

Now let’s see DQDL labels in action by applying AnyCompany’s rule set to actual data through an AWS Glue ETL pipeline. This section assumes you’re familiar with AWS Glue EvaluateDataQuality transform and basic extract, transform, and load (ETL) job creation.

We use AWS Glue EvaluateDataQuality transform within an ETL job to process our customer dataset and apply our labeled rule set. The transform generates two types of outputs: rule-level outcomes that show which rules passed or failed with their associated labels and row-level results that identify specific records and the labeled rules they violated.

By default, labels are excluded from row-level results. However, by enabling them you can analyze data quality results at both the individual record level and across organizational dimensions such as teams and criticality levels.

To enable labels in row-level results, you must configure the additionalOptions parameter in your EvaluateDataQuality transform. The key setting is "rowLevelConfiguration.ruleWithLabels":"ENABLED", which instructs AWS Glue to include label metadata for each rule evaluation at the individual record level.

Here’s how to implement an ETL pipeline that applies our AnyCompany’s rule set with labels enabled:

import sys
from awsglue.transforms import *
from awsglue.utils import getResolvedOptions
from pyspark.context import SparkContext
from awsglue.context import GlueContext
from awsglue.job import Job
from awsgluedq.transforms import EvaluateDataQuality
from awsglue.dynamicframe import DynamicFrame
import boto3

def create_table(athena,s3_bucket,df,db_name,table_name):
    ddl = spark.sparkContext._jvm.org.apache.spark.sql.types.DataType.fromJson(df.schema.json()).toDDL()
    ddl_stmt_string=f"""CREATE EXTERNAL TABLE IF NOT EXISTS {db_name}.{table_name} ({str(ddl)}) ROW FORMAT SERDE 'org.apache.hadoop.hive.ql.io.parquet.serde.ParquetHiveSerDe' STORED AS INPUTFORMAT 'org.apache.hadoop.hive.ql.io.parquet.MapredParquetInputFormat' OUTPUTFORMAT 'org.apache.hadoop.hive.ql.io.parquet.MapredParquetOutputFormat' LOCATION 's3://{s3_bucket}/label/{table_name}/'"""
    athena.start_query_execution(QueryString=ddl_stmt_string,ResultConfiguration={'OutputLocation': f"s3://{s3_bucket}/athena_results/"})

args = getResolvedOptions(sys.argv, ['JOB_NAME'])

sc = SparkContext()
glueContext = GlueContext(sc)
spark = glueContext.spark_session
job = Job(glueContext)
job.init(args['JOB_NAME'], args)

rules="""
DefaultLabels = ["team"="data-team", "criticality"="medium", "regulation"="none", "sla"="24h", "impact"="medium"] 
Rules = [ 
        IsComplete "c_customer_id" labels=["team"="analytics", "criticality"="high", "sla"="15m", "impact"="high"], 
        ColumnValues "c_customer_id" matches "e.*" labels=["team"="analytics", "criticality"="medium", "impact"="low"], 
        ColumnLength "c_city" > 6 labels=["team"="marketing", "criticality"="medium", "sla"="4h", "impact"="medium"], 
        IsComplete "c_name" labels=["team"="marketing", "sla"="4h"], 
        ColumnValues "c_age" >= 21 labels=["team"="compliance", "criticality"="high", "regulation"="age21", "impact"="high"] with threshold > 0.99, 
        IsComplete "c_birth_date" labels=["team"="compliance", "criticality"="medium", "regulation"="gdpr", "impact"="medium"], 
        IsComplete "c_creditissuer" labels=["team"="finance", "impact"="high"], 
        ColumnValues "c_creditcardnumber" > 100000000000 labels=["team"="finance", "criticality"="high", "regulation"="payment", "impact"="high"] with threshold > 0.95 
        ]
"""

s3_bucket="REPLACE"

row_level_table="dqrowlevel"
rule_level_table="dqrulelevel"
db_name="default"

additional_options={}
additional_options["observations.scope"]="ALL"
additional_options["performanceTuning.caching"]="CACHE_INPUT"

additional_options["rowLevelConfiguration.ruleWithLabels"]="ENABLED"

df = spark.read.option("header", "true").option("inferSchema", "true").csv("s3://aws-data-analytics-workshops/aws_glue/aws_glue_data_quality/data/customers/")

anycompany_customers=DynamicFrame.fromDF(df, glueContext, "anycompany_customers")

dq_check = EvaluateDataQuality().process_rows(frame=anycompany_customers, ruleset=rules, publishing_options={"dataQualityEvaluationContext": "dq_check","enableDataQualityCloudWatchMetrics": True, "enableDataQualityResultsPublishing": True}, additional_options=additional_options)

rowlevel = SelectFromCollection.apply(dfc=dq_check, key="rowLevelOutcomes", transformation_ctx="rowlevel")
rulelevel = SelectFromCollection.apply(dfc=dq_check, key="ruleOutcomes", transformation_ctx="rulelevel")

rowlevel_df=rowlevel.toDF()
rulelevel_df=rulelevel.toDF()

rowlevel_df.write.mode("overwrite").parquet(f"s3://{s3_bucket}/label/{row_level_table}/")
rulelevel_df.write.mode("overwrite").parquet(f"s3://{s3_bucket}/label/{rule_level_table}/")

athena = boto3.client('athena')
create_table(athena,s3_bucket,rowlevel_df,db_name,row_level_table)
create_table(athena,s3_bucket,rulelevel_df,db_name,rule_level_table)

job.commit()

To run this example, update the s3_bucket variable with your own Amazon Simple Storage Service (Amazon S3) bucket name, then create and execute the ETL job in AWS Glue.

After the job is completed, you’ll find:

  • Rule-level and row-level results stored in your S3 bucket
  • Two new tables automatically created in your default database: dqrulelevel and dqrowlevel

In the next section, we query these tables using Amazon Athena to analyze the labeled data quality outcomes and extract actionable insights.

Analyzing data quality results by labels using Amazon Athena

We’ve stored our labeled data quality results in Amazon S3 and as a table in the AWS Glue data catalog. Now, we can use Amazon Athena to analyze these results across the organizational dimensions captured in your labels. The labeled metadata transforms raw data quality outcomes into actionable business intelligence that drives targeted remediation and strategic decision-making.

Querying row-level results

With labels stored alongside row-level outcome, you can query specific records that failed data quality checks based on label criteria. For example, the following query identifies individual customer records that failed high criticality compliance rules. You can use it to quickly locate and remediate problematic data for regulatory or business-critical use cases:

SELECT
c_customer_id,
c_age,
failed_rule
FROM (
SELECT *
FROM dqrowlevel
WHERE dataqualityevaluationresult = 'Failed'
)
CROSS JOIN UNNEST(dataqualityrulesfail) AS t(failed_rule)
WHERE failed_rule LIKE '%criticality"="high"%'
AND failed_rule LIKE '%team"="compliance"%'
LIMIT 5;

You can see the query results above showing failed records filtered by 'high' criticality and 'compliance' team labels.

Querying rule-level results

Now that we have stored rule-level outcomes with labels, we can run aggregation queries to analyze failures across different dimensions. For example, the following query groups failed rules by criticality and team to identify which teams have the most high-severity failures. You can use it to prioritize remediation efforts and allocate resources effectively:

SELECT 
    labels['team'] AS team,
    labels['criticality'] AS criticality,
    COUNT(*) AS failed_count
FROM dqrulelevel
WHERE outcome = 'Failed'
GROUP BY labels['criticality'], labels['team']
ORDER BY failed_count DESC;

The following screenshot shows aggregated failure counts grouped by team and criticality level.

Viewing data quality results using AWS CLI

Beyond querying results in Athena, you can also retrieve data quality outcomes directly using the AWS Command Line Interface (AWS CLI). This is useful for automation, scripting, and integrating data quality checks into continuous integration and continuous delivery (CI/CD) pipelines.

To list data quality results for your ETL job, enter the following:

aws glue list-data-quality-results --filter '{"JobName":"<your-job-name>"}'

You can see in the above screenshot that the resultant JSON includes a ResultId for each data quality run.

To retrieve details of a specific result, enter the following:

aws glue get-data-quality-result --result-id <result-id>

The output includes a Labels object for each rule in the RuleResults array, containing the label key-value pairs you defined. This provides programmatic access to the same labeled data quality results, which can be useful for automation and scripting workflows.

Cleanup

To avoid incurring ongoing charges, delete the resources created in this post:

  • To delete the S3 folders containing the data quality results, follow the directions at Deleting Amazon S3 objects.
  • To delete the ETL job you created for the test, follow the directions at Delete jobs in the AWS Glue User Guide.
  • To delete the AWS Glue Data Catalog dqrulelevel and dqrowlevel tables, follow the directions at DeleteTable in the AWS Glue Web API Reference.

Conclusion

AWS Glue DQDL labels add organizational context to data quality management by attaching business metadata directly to validation rules. This helps teams identify rule ownership, prioritize failures, and coordinate remediation efforts more effectively.Throughout this post, we’ve seen how AnyCompany moved from managing hundreds of generic rules to implementing a labeled system where data quality results include team ownership and business context. Marketing teams can identify their email validation failures, compliance teams can focus on regulatory violations, and finance teams can address payment-related issues without manual coordination.To implement DQDL Labels in your organization:

  • Start simple – Begin with basic organizational dimensions such as team ownership, criticality levels, and SLA requirements. Expand your labeling approach as needed.
  • Establish standards – Define your label taxonomy up front, including default values for unused dimensions. This consistency supports analytics across teams.
  • Integrate gradually – Add labels to existing rule sets during routine maintenance.
  • Use analytics – Apply the Athena query patterns from this post to build tools such as dashboards and alerting workflows.
  • Build smart automation – Explore creating alerts and notifications tailored to your business criticality and SLA definitions. For example, configure immediate notifications for high-criticality compliance failures while batching low-priority marketing issues into daily reports.

We look forward to seeing how you implement DQDL labels in your organization and expand beyond the examples we’ve covered here. To dive into the AWS Glue Data Quality APIs, refer to Data Quality API documentation. To learn more about AWS Glue Data Quality, check out AWS Glue Data Quality.


About the authors

Arun A K

Arun A K

Arun is a Senior Big Data Specialist Solutions Architect at Amazon Web Services (AWS). He helps customers design and scale data platforms that power innovation through analytics and AI. Arun is passionate about exploring how data and emerging technologies can solve real-world problems. Outside of work, he enjoys sharing knowledge with the tech community and spending time with his family.

Annie Wang

Annie Wang

Annie is a Software Development Engineer at AWS Glue. She focuses on building data quality features, including DQDL, that help customers define, monitor, and validate data quality across their pipelines. She is passionate about making data reliability easier for customers.

Roshin Babu

Roshin Babu

Roshin is a Sr. Specialist Solutions Architect at AWS, where he collaborates with the sales team to support public sector clients. When he’s not working, Roshin is passionate about exploring new destinations, discovering great food, and enjoying soccer both as a player and fan.

Enterprise scale in-place migration to Apache Iceberg: Implementation guide

Post Syndicated from Mihir Borkar original https://aws.amazon.com/blogs/big-data/enterprise-scale-in-place-migration-to-apache-iceberg-implementation-guide/

Organizations managing large-scale analytical workloads increasingly face challenges with traditional Apache Parquet-based data lakes with Hive-style partitioning, including slow queries, complex file management, and limited consistency guarantees. Apache Iceberg addresses these pain points by providing ACID transactions, seamless schema evolution, and point-in-time data recovery capabilities that transform how enterprises handle their data infrastructure.

In this post, we demonstrate how you can achieve migration at scale from existing Parquet tables to Apache Iceberg tables. Using Amazon DynamoDB as a central orchestration mechanism, we show how you can implement in-place migrations that are highly configurable, repeatable, and fault-tolerant—unlocking the full potential of modern data lake architectures without extensive data movement or duplication.

Solution overview

When performing in-place migration, Apache Iceberg uses its ability to directly reference existing data files. This capability is only supported for formats such as Parquet, ORC, and Avro, because these formats are self-describing and include consistent schema and metadata information. Unlike raw formats such as CSV or JSON, they enforce structure and support efficient columnar or row-based access, which allows Iceberg to integrate them without rewriting the data.

In this post, we demonstrate how you can migrate an existing Parquet-based data lake that isn’t cataloged in AWS Glue by using two methodologies:

  • Apache Iceberg migrate and register_table approach. Ideal for converting existing Hive-registered Parquet tables into Iceberg-managed tables.
  • Iceberg add_files approach. Best suited for quickly onboarding raw Parquet data into Iceberg without rewriting files.

The solution also incorporates a DynamoDB table that acts as a scalable control plane, so you can perform in-place migration of your data lake from Parquet format to Iceberg format.

The following diagram shows different methodologies that you can use to achieve this in-place migration of your Hive-style partitioned data lake:

AWS data pipeline architecture diagram showing data flow from Amazon DynamoDB through Amazon EMR and AWS Glue to a Data Lake and Apache Iceberg Lakehouse, both using Parquet format, within an AWS Region.

You use DynamoDB to track the migration state, handling retries and recording errors and outcomes. This provides the following benefits:

  • Centralized control over which Amazon Simple Storage Service (Amazon S3) paths need migration.
  • Lifecycle tracking of each dataset through migration stages.
  • Capture and audit errors on a per-path basis.
  • Enable re-runs by updating stateful flags or clearing failure messages.

Prerequisites

Before you begin, you need:

Create sample Parquet dataset as a source

You can create the sample Parquet dataset for testing the different methodologies using the Athena query editor. Replace <amzn-s3-demo-bucket> with an available bucket in your account.

  1. Create an AWS Glue database(test_db), if not present.
    CREATE DATABASE IF NOT EXISTS test_db

  2. Create a sample Parquet table (table1) and add to be used for testing the add_files approach.
    CREATE TABLE table1
    WITH (
      external_location = 's3://<amzn-s3-demo-bucket>/table1/',
      format = 'PARQUET',
      partitioned_by = ARRAY['date', 'hour']
    )
    AS
    SELECT 
      1 as id,
      'John Doe' as name,
      25 as age,
      'Engineer' as job_title,
      current_date as created_date,
      current_date as date,
      hour(current_timestamp) as hour
    UNION ALL
    SELECT 2, 'Jane Smith', 30, 'Manager', current_date, current_date, hour(current_timestamp)
    UNION ALL  
    SELECT 3, 'Bob Johnson', 35, 'Analyst', current_date, current_date, hour(current_timestamp);

  3. Create a sample Parquet table (table2) and add data to be used for testing the migrate and register_table approach. Replace <amzn-s3-demo-bucket> with your bucket name.
    CREATE TABLE table2
    WITH (
      external_location = 's3://<amzn-s3-demo-bucket>/table2/',
      format = 'PARQUET',
      partitioned_by = ARRAY['date', 'hour']
    )
    AS
    SELECT 
      1 as id,
      'John Doe' as name,
      25 as age,
      'Engineer' as job_title,
      current_date as created_date,
      current_date as date,
      hour(current_timestamp) as hour
    UNION ALL
    SELECT 2, 'Jane Smith', 30, 'Manager', current_date, current_date, hour(current_timestamp)
    UNION ALL  
    SELECT 3, 'Bob Johnson', 35, 'Analyst', current_date, current_date, hour(current_timestamp);

  4. Drop the tables from the Data Catalog because you only need Parquet data with the Hive-style partitioning structure.
    DROP TABLE IF EXISTS test_db.table1

Create a DynamoDB control table

Before beginning the migration process, you must create a DynamoDB table that serves as the control plane. This table maps source Amazon S3 paths to their corresponding Iceberg database and table destinations, enabling systematic tracking of the migration process.

To implement this control mechanism, create a table with the following structure:

  • A primary key s3_path that stores the source Parquet data location
  • Two attributes that define the target Iceberg location:
    • target_db_name
    • target_table_name

To create the DynamoDB control table

  1. Create the Amazon DynamoDB table using the following AWS CLI command:
    aws dynamodb create-table \
    --table-name migration-control-table \
    --attribute-definitions \
    AttributeName=s3_path,AttributeType=S \
    --key-schema \
    AttributeName=s3_path,KeyType=HASH \
    --billing-mode PAY_PER_REQUEST \
    --region <REGION>

  2. Verify the table is created successfully. Replace <REGION> with the AWS Region where your data is stored:
    aws dynamodb describe-table --table-name migration-control-table --region <REGION>

  3. Create a migration_data.json file with the following contents.
    In this example:

    • Replace <amzn-s3-demo-bucket> and <TablePrefix>with the name of your S3 bucket and prefix containing the Parquet data
    • Replace <DatabaseName> with the name of your target Iceberg database
    • Replace <TableName> with the name of your target Iceberg table
    {
        "your-migration-table": [
            {
                "PutRequest": {
                    "Item": {
                        "s3_path": {"S": "s3://<amzn-s3-demo-bucket>/table1/"},
                        "target_db_name": {"S": "test_db"},
                        "target_table_name": {"S": "table1"}
                    }
                }
            },
            {
                "PutRequest": {
                    "Item": {
                        "s3_path": {"S": "s3://<amzn-s3-demo-bucket>/table2/"},
                        "target_db_name": {"S": "test_db"},
                        "target_table_name": {"S": "table2"}
                    }
                }
            },
            {
                "PutRequest": {
                    "Item": {
                        "s3_path": {"S": "s3://<amzn-s3-demo-bucket>/<TablePrefix>/"},
                        "target_db_name": {"S": "<DatabaseName>"},
                        "target_table_name": {"S": "<TableName>"}
                    }
                }
            }
        ]
    }

    This file defines the mapping between Amazon S3 paths and their corresponding Iceberg table destinations.

  4. Run the following CLI command to load the DynamoDB control table.
    aws dynamodb batch-write-item \
    --request-items file://migration_data.json \
    --region <REGION;>

Migration methodologies

In this section, you explore two methodologies for migrating your existing Parquet tables to Apache Iceberg format:

  • Apache Iceberg migrate and register_table approach – This approach first converts your Parquet table to Iceberg format using the native migrate procedure, followed by registering it in AWS Glue using the register_table procedure.
  • Apache Iceberg add_files approach – This method creates an empty Iceberg table and uses the add_files procedure to import existing Parquet data files without physically moving them.

Apache Iceberg migrate and register_table procedure

Use the Apache Iceberg Migrate procedure that is used for in-place conversion of an existing Hive or Parquet table into an Iceberg-managed table. Thereafter, you can use the Apache Iceberg RegisterTable procedure to register the respective table in AWS Glue.

AWS workflow diagram showing DynamoDB to Apache Iceberg migration using Amazon EMR with Hive Metastore for migration and Glue Metastore for registration, displaying configuration tables at each stage.

Migrate

  1. In your EMR cluster with Hive as the metastore, create a PySpark session with the following Iceberg Packages:
    pyspark \
    --name "Iceberg Migration" \
    --conf "spark.jars=/usr/share/aws/iceberg/lib/iceberg-spark3-runtime.jar" \
    --conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions \
    --conf spark.sql.catalog.spark_catalog=org.apache.iceberg.spark.SparkSessionCatalog \
    --conf spark.sql.catalog.spark_catalog.type=hive

    This post uses Iceberg v1.9.1 (Amazon EMR build), which is native to Amazon EMR 7.11. Always verify the latest supported version and update package coordinates accordingly.

  2. Next, create your corresponding table in your Hive catalog (you can skip this step if you already have tables created in your hive catalog). Replace <amzn-s3-demo-bucket> with the name of your S3 bucket.
    In the following snippet, change or remove the PARTITIONED BY command based on the partition strategy of your table, the MSCK Repair table command should only be run if your respective table is partitioned.

    #You can automate this for production Scaling with DynamoDB as control table 
    s3_path = "s3://<amzn-s3-demo-bucket>/table1/"
    target_db_name = "test_db"
    target_table_name = "table1"
    # Read data in a dataframe to infer schema
    df = spark.read.parquet(s3_path)
    df.createOrReplaceTempView("temp_view")
    # Get schema as string
    schema = spark.table("temp_view").schema
    schema_string = ", ".join([f"{field.name} {field.dataType.simpleString()}" for field in schema])
    # Create Database If not exists 
    spark.sql(f"CREATE DATABASE IF NOT EXISTS {target_db_name}").show()
    # full_table_name= test_db.table1
    full_table_name = f"{target_db_name}.{target_table_name}"
    # Create table
    spark.sql(f"""
    CREATE TABLE IF NOT EXISTS {full_table_name} (
        {schema_string}
    )
    STORED AS PARQUET
    PARTITIONED BY (date, hour)
    LOCATION '{s3_path}'
    """)
    # Refresh, repair, and validate
    spark.sql(f"REFRESH TABLE {full_table_name}")
    spark.sql(f"MSCK REPAIR TABLE {full_table_name}")

  3. Convert the Parquet table to an Iceberg table in Hive
    # Run migration procedure
    spark.sql(f"CALL spark_catalog.system.migrate('{full_table_name}')")
    # Validate that the table is successfully migrated 
    spark.sql(f"DESCRIBE FORMATTED {full_table_name}").show(truncate=False)

Run the migrate command to convert the Parquet-based table to an Iceberg table, creating the metadata folder and the metadata.json file therein

You can stop at this point if you don’t intend to migrate your existing iceberg table from Hive to the Data Catalog.

Register

  1. Sign in to the AWS Glue as Spark Catalog enabled EMR cluster.
  2. Register the Iceberg table to your Data Catalog.

    Create the session with the respective Iceberg Packages. Replace <amzn-s3-demo-bucket> with your bucket name, and <warehouse> with warehouse directory.

    pyspark \
    --conf "spark.jars=/usr/share/aws/iceberg/lib/iceberg-spark3-runtime.jar" \
    --conf "spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions" \
    --conf "spark.sql.catalog.glue_catalog=org.apache.iceberg.spark.SparkCatalog" \
    --conf "spark.sql.catalog.glue_catalog.warehouse= s3://<amzn-s3-demo-bucket>/<warehouse>/"  \
    --conf "spark.sql.catalog.glue_catalog.catalog-impl=org.apache.iceberg.aws.glue.GlueCatalog" \
    --conf "spark.sql.catalog.glue_catalog.io-impl=org.apache.iceberg.aws.s3.S3FileIO"

  3. Run the register_table command to make the Iceberg table visible in AWS Glue.
    • register_table registers an existing Iceberg table’s metadata file (metadata.json) with a catalog(glue_catalog) so that Spark (and other engines) can query it.
    • The procedure creates a Data Catalog entry for the table, pointing it to the given metadata location.

    Replace <amzn-s3-demo-bucket> and <metadata-prefix> with the name of your S3 bucket and metadata prefix name.

    Ensure that your EMR Spark Cluster has been configured with appropriate AWS Glue permissions

    # You can automate this for production Scaling with DynamoDB as control table
    metadata_location = "s3://<amzn-s3-demo-bucket>/table1/metadata/<metadata-prefix>.metadata.json"
    target_db_name = "test_db"
    target_table_name = "table1"
    full_table_name = f"{target_db_name}.{target_table_name}"
    # Register existing Iceberg table metadata in Glue Catalog
    spark.sql(f"CALL glue_catalog.system.register_table('{full_table_name}', '{metadata_location}')")
    # Set table properties (example: Iceberg format version 2)
    spark.sql(f"ALTER TABLE glue_catalog.{full_table_name} SET TBLPROPERTIES('format-version'='2')")

  4. Validate that the Iceberg table is now visible in the Data Catalog.
    # Lookout for format as iceberg/parquet
    spark.sql("SHOW TBLPROPERTIES glue_catalog.test_db.table1").show()

Apache Iceberg’s add_files procedure

AWS workflow diagram showing DynamoDB to Apache Iceberg migration using AWS Glue Add_Files procedure, displaying input configuration and output status tables with metadata location and registration confirmation.

Here, you’re going to use Iceberg’s add_files procedure to import raw data files (Parquet, ORC, Avro) into an existing Iceberg table by updating its metadata. This procedure works for both Hive and Data Catalog, it doesn’t physically move or rewrite the files—it only registers them so Iceberg can manage them.

This methodology comprises the following steps:

  1. Create an empty Iceberg table in AWS Glue.
    Because the add_files procedure expects the iceberg table to be already present, you need to create an empty Iceberg table by inferring the table schema.
  2. Register existing data locations to the Iceberg table

Using the add_files procedure in a Glue-backed Iceberg catalog will register the target S3 path along with all its subdirectories to the empty Iceberg table created in the previous step.

You can consolidate both steps into a single Spark job. For the following AWS Glue job, you have specified iceberg as a value for the --datalake-formats job parameter. See the AWS Glue job configuration documentation for more details.

Replace <amzn-s3-demo-bucket> with your S3 bucket name and <warehouse> with warehouse directory.

from pyspark.sql import SparkSession
import logging
logging.basicConfig(level=logging.INFO)
logger = logging.getLogger(__name__)
target_db_name = "test_db"
target_table_name = "table2"
s3_path = "s3://<amzn-s3-demo-bucket>/table2"
# Set to None or [] for unpartitioned
partitioned_cols = ["date", "hour"]  
spark = SparkSession.builder \
    .appName("Iceberg Add Files") \
    .config("spark.sql.extensions", "org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions") \
    .config("spark.sql.catalog.glue_catalog", "org.apache.iceberg.spark.SparkCatalog") \
    .config("spark.sql.catalog.glue_catalog.catalog-impl", "org.apache.iceberg.aws.glue.GlueCatalog") \
    .config("spark.sql.catalog.glue_catalog.io-impl", "org.apache.iceberg.aws.s3.S3FileIO") \
    .config("spark.sql.catalog.glue_catalog.warehouse", "s3://<amzn-s3-demo-bucket>/<warehouse>/") \
    .getOrCreate()
full_table_name = f"glue_catalog.{target_db_name}.{target_table_name}"
# Read schema from one file (schema inference)
df = spark.read.parquet(s3_path)
schema = df.schema
# Create empty Iceberg table
empty_df = spark.createDataFrame([], schema)
if partitioned_cols:
    empty_df.writeTo(full_table_name).using("iceberg").partitionedBy(*partitioned_cols). .tableProperty("format-version", "2").create()
else:
    empty_df.writeTo(full_table_name).using("iceberg").tableProperty("format-version", "2").create()
logger.info(f"Created empty Iceberg table: {full_table_name}")
spark.sql(f"""
CALL glue_catalog.system.add_files(
  '{target_db_name}.{target_table_name}',
  'parquet.`{s3_path}`'
)
""")

When working with non-Hive partitioned datasets, a direct migration to Apache Iceberg using add_files might not behave as expected. See Appendix C for more information.

Considerations

Let’s explore two key considerations that you should address when implementing your migration strategy.

State management using DynamoDB control table

Use the following sample code snippet to update the state of DynamoDB table:

def update_dynamodb_record(self, s3_path, metadata_loc=None, error_msg=None):
    # Get current error message
    try:
        response = self.dynamodb.get_item(
            TableName='migration-control-table',
            Key={'s3_path': {'S': s3_path}}
        )
        current_error = response.get('Item', {}).get('error_message', {}).get('S', '')
    except:
        current_error = ""
    if error_msg:
        # Error case
        error_msg = (error_msg or "Unknown error")[:1000]
        update_expr = "SET error_message = :err"
        attr_values = {':err': {'S': error_msg}}
        if current_error:
            update_expr += ", prev_error_message = :prev"
            attr_values[':prev'] = {'S': current_error}
        update_kwargs = {'TableName': 'Iceberg_migration','Key': {'s3_path': {'S': s3_path}},'UpdateExpression': update_expr,'ExpressionAttributeValues': attr_values}
        self.logger.error(f"Set error for {s3_path}: {error_msg}")
    else:
        # Success case
        update_kwargs = {
            'TableName': 'Iceberg_migration',
            'Key': {'s3_path': {'S': s3_path}},
            'UpdateExpression': 'SET #s = :status, #m = :meta, #p = :prev, #e = :err',
            'ExpressionAttributeNames': {'#s': 'status','#p': 'prev_error_message','#e': 'error_message','#m': 'metadata_location'
            },
            'ExpressionAttributeValues': {
                ':status': {'S': 'Iceberg_Metadata_Populated and Registered'},
                ':prev': {'S': current_error},
                ':err': {'S': ''},
                ':meta': {'S': metadata_loc}
            }
        }
        self.logger.info(f"Updated DynamoDB status for {s3_path}: {metadata_loc}")

This ensures that any errors are logged and saved to DynamoDB as error_message. On successive retries, previous errors move to prev_error_message and new errors overwrite error_message. Successful operations clear error_message and archive the last error.

Protecting your data from unintended deletion

To protect your data from unintended deletion, never delete data or metadata files from Amazon S3 directly. Iceberg tables that are registered in AWS Glue or Athena are managed tables and should be deleted using the DROP TABLE command from Spark or Athena. The DROP TABLE command deletes both the table metadata and the underlying data files in S3. See Appendix D for more information.

Clean up

Complete the following steps to clean up your resources:

  1. Delete the DynamoDB control table
  2. Delete the database and tables
  3. Delete the EMR clusters and AWS Glue job used for testing

Conclusion

In this post, we showed you how to modernize your Parquet-based data lake into an Apache Iceberg–powered lakehouse without rewriting or duplicating data. You learned two complementary approaches for this in-place migration:

  • Migrate and register – Ideal for converting existing Hive-registered Parquet tables into Iceberg-managed tables.
  • add_files – Best suited for quickly onboarding raw Parquet data into Iceberg without rewriting files.

Both approaches benefit from DynamoDB centralized state tracking, which enables retries, error auditing, and lifecycle management across multiple datasets.

By combining Apache Iceberg with Amazon EMR, AWS Glue, and Amazon DynamoDB, you can create a production-ready migration pipeline that is observable, automated, and straightforward to extend to future data format upgrades. This pattern forms a solid foundation for building an Iceberg-based lakehouse on AWS, helping you achieve faster analytics, better data governance, and long-term flexibility for evolving workloads.

To get started, try implementing this solution using the sample tables (table1 and table2) that you created using Athena queries. we encourage you to share your migration experiences and questions in the comments.


Appendix A — Creating an EMR cluster for Hive metastore using console and AWS CLI

Console steps:

  1. Open AWS Management Console for Amazon EMR and choose Create cluster.
  2. Select Spark or Hive under applications.
  3. Under AWS Glue Data Catalog settings, make sure the following options are not selected:
    • Use for Hive table metadata
    • Use for Spark table metadata
  4. Configure SSH access (KeyName).
  5. Configure network (VPC, subnets, SGs) to allow access to S3.

AWS CLI steps:

aws emr create-cluster \
  --region us-east-1 \
  --name "IcebergHiveCluster711" \
  --release-label emr-7.11.0 \
  --applications Name=Hive Name=Spark Name=Hadoop \
  --ec2-attributes '{"KeyName":"<key-pair>","SubnetId":"<subnet-id>"}'  \
  --instance-groups '[
    {
      "Name":"Master",
      "InstanceGroupType":"MASTER",
      "InstanceType":"m5.xlarge",
      "InstanceCount":1
    },
    {
      "Name":"Workers",
      "InstanceGroupType":"CORE",
      "InstanceType":"m5.xlarge",
      "InstanceCount":2
    }
  ]' \
  --use-default-roles

Appendix B — EMR cluster with AWS Glue as Spark Metastore

Console steps:

  1. Open the Amazon EMR console, choose Create cluster and then select EMR Serverless or provisioned EMR.
  2. Under Software Configuration, verify that Spark is installed.
  3. Under AWS Glue Data Catalog settings, select Use Glue Data Catalog for Spark metadata.
  4. Configure SSH access (KeyName).
  5. Configure network settings (VPC, subnets, and security groups) to allow access to Amazon S3 and AWS Glue.

AWS CLI (provisioned Amazon EMR):

aws emr create-cluster \
  --region us-east-1 \
  --name "IcebergGlueCluster711" \
  --release-label emr-7.11.0 \
  --applications Name=Spark Name=Hadoop \
  --ec2-attributes '{"KeyName":"<key-pair>","SubnetId":"<subnet-id>"}' \
  --instance-groups '[
    {
      "Name":"Master",
      "InstanceGroupType":"MASTER",
      "InstanceType":"m5.xlarge",
      "InstanceCount":1
    },
    {
      "Name":"Workers",
      "InstanceGroupType":"CORE",
      "InstanceType":"m5.xlarge",
      "InstanceCount":2
    }
  ]' \
 --configurations '[{"Classification":"spark-hive-site","Properties":{"hive.metastore.client.factory.class":"com.amazonaws.glue.catalog.metastore.AWSGlueDataCatalogHiveClientFactory"}}]' \
 --use-default-roles

Appendix C — Non-Hive partitioned datasets and Iceberg add_files

This appendix explains why a direct in-place migration using an add_files-style procedure might not behave as expected for datasets that aren’t Hive-partitioned and shows recommended fixes and examples.

AWS Glue and Athena follow Hive-style partitioning, where partition column values are encoded in the S3 path rather than inside the data files. For example, following the Parquet dataset created in the Create Sample Parquet Dataset as a source section of this post:

s3://amzn-s3-demo-bucket/events/event_date=2024-09-01/hour=5/part-0000.parquet
s3://amzn-s3-demo-bucket/events/event_date=2024-09-02/hour=5/part-0001.parquet
  • Partition columns (event_date, hour) are represented in the folder structure.
  • Non-partition columns (for example, id, name, age) remain inside the Parquet files.
  • Iceberg add_files can correctly map partitions based on the folder path, even if partition columns are missing from the Parquet file itself.

Partition column

Stored in path

Stored in file

Athena or AWS Glue and Iceberg behavior

event_date Yes Yes Partitions inferred correctly
hour Yes No Partitions still inferred from path

Non-Hive partitioning layout (problem case)

s3://amzn-s3-demo-bucket/events/date/part-0000.parquet
s3://amzn-s3-demo-bucket/events/date/part-0001.parquet
  • No partition columns in the path.
  • File might not contain partition columns.

If you try to create an empty Iceberg table and directly load it using add_files on a non-hive layout, the following happens:

  1. Iceberg cannot automatically map partitions, add_files operations fail or register files with incorrect or missing partition metadata.
  2. Queries in Athena or AWS Glue will return unexpected NULLs or incomplete results.
  3. Successive incremental writes using add_files will fail.

Recommended approaches:

Create an AWS Glue table and use the Iceberg snapshot procedure:

  1. Create a table in AWS Glue pointing to your existing Parquet dataset.

You might need to manually provide the schema because glue crawler might fail to automatically infer it for you.

  1. Use Iceberg’ s snapshot procedure to convert and move the AWS Glue table into your target Iceberg table.

This works because Iceberg relies on AWS Glue for schema inference, so this approach ensures correct mapping of columns and partitions without rewriting the data. For more information, see Snapshot procedure.


Appendix D — Understanding table types: Managed compared to external

By default, all non-Iceberg tables created in AWS Glue or Athena are external tables, Athena doesn’t manage the underlying data. If you use CREATE TABLE without the EXTERNAL keyword for non-Iceberg tables, Athena issues an error.

However, when dealing with Iceberg tables, AWS Glue and Athena also manage the underlying data for the respective tables, so these tables are treated as internal tables.

Running DROP TABLE on Iceberg tables will delete the table and the underlying data.

The following table describes how the effect of DELETE and DROP TABLE actions on Iceberg tables in AWS Glue and Athena:

Operation What it does Effect on S3 data
DELETE FROM mydb.products_iceberg WHERE date = 2025-10-06; Creates new snapshot, hides deleted rows Data files stay until cleanup
DROP TABLE test_db.table1; Deletes table and all data Files are permanently removed

About the authors

Mihir Borkar

Mihir Borkar

Mihir is a seasoned AWS Data Architect with nearly a decade of experience designing and implementing enterprise-scale data solutions on AWS. He specializes in modernizing data architectures using AWS data analytical services, designing scalable data lakes and analytics platforms with a focus on efficient, cost-effective solutions. In his free time, Mihir loves to read about emerging cloud technologies and explore latest developments in AI/ML.

Amit Maindola

Amit Maindola

Amit is a Senior Data Architect with AWS ProServe team focused on data engineering, analytics, and AI/ML at Amazon Web Services. He helps customers in their digital transformation journey and enables them to build highly scalable, robust, and secure cloud-based analytical solutions on AWS to gain timely insights and make critical business decisions.

Arghya Banerjee

Arghya Banerjee

Arghya is a Sr. Solutions Architect at AWS in the San Francisco Bay Area, focused on helping customers adopt and use the AWS Cloud. He is focused on big data, data lakes, streaming and batch analytics services, and generative AI technologies.

Access Snowflake Horizon Catalog data using catalog federation in the AWS Glue Data Catalog

Post Syndicated from Andries Engelbrecht original https://aws.amazon.com/blogs/big-data/access-snowflake-horizon-catalog-data-using-catalog-federation-in-the-aws-glue-data-catalog/

This is a guest post by Andries Engelbrecht, Principal Partner Solutions Engineer at Snowflake, in partnership with AWS.

AWS announced a new catalog federation feature that allows you to directly access data from Snowflake Horizon Catalog through the AWS Glue Data Catalog. This integration enables you to discover and query Horizon Catalog data in Iceberg format through REST endpoints while applying fine-grained access controls using AWS Lake Formation. The new catalog federation combined with Snowflake’s catalog-linked database feature means users can access data stored across AWS and Snowflake from a single point of entry, reducing data movement and associated costs by eliminating the need to duplicate data across platforms.

In this post, we show you how to connect the AWS Glue Data Catalog to Snowflake Horizon Catalog and query the data using AWS analytics services. We cover how to set up catalogs in Horizon Catalog and configure required permissions, create and configure the federation connection in AWS Glue, implement fine-grained access controls using AWS Lake Formation, and finally, query federated tables using Amazon Athena. This step-by-step approach guides you through the complete process of establishing a integration between your Snowflake and AWS data environments.

Business examples and key benefits

Catalog federation enables several critical business scenarios while delivering key operational and strategic benefits.

Common examples

This federation capability addresses several key business scenarios:

  • Governed, cross-platform analytics: Query data across AWS and Snowflake environments to improve data-driven decision making without data movement or duplication
  • Data mesh implementation: Enable secure and federated data discovery while maintaining domain-oriented ownership
  • Compliance management: Implement consistent access controls and auditing across platforms

Key benefits

  • Operational efficiency: Eliminate data duplication and reduce Extract Transform Load (ETL) workloads
  • Enhanced security: Centralize access control through AWS Lake Formation with fine-grained permissions
  • Cost optimization: Minimize data transfer and storage costs across platforms
  • Improved agility: Enable faster time to insights with direct query access
  • Simplified governance: Maintain unified compliance and audit framework

Solution overview

The solution uses catalog federation in the AWS Glue Data Catalog to integrate with Snowflake Horizon Catalog. This integration supports both Snowflake Horizon, where the catalog is internal to Snowflake, and external catalogs such as Apache Polaris, Snowflake Open Catalog (a managed service that hosts Apache Polaris), and others.

The following diagram illustrates how AWS Glue Data Catalog federates with Snowflake Horizon Catalog, enabling customers to directly access Iceberg-format data managed by Snowflake Horizon Catalog through the Glue Data Catalog.

Architecture diagram showing integration between AWS services and Snowflake using federated catalog connections through Apache Iceberg REST API.

The integration works through three main components:

  1. Authentication: Uses OAuth2 credentials of Snowflake principal
  2. Access Control: AWS Lake Formation manages fine-grained permissions
  3. Query Access: AWS Analytics services like Amazon Athena can directly query the federated tables

Now, we walk through the step-by-step process of setting up this integration.

Prerequisites

Before you begin, confirm you have the following:

Configure Snowflake Horizon Catalog for Iceberg external access

Snowflake Horizon Catalog already supports managing Iceberg tables. For this walkthrough, you need to create Snowflake-managed Iceberg tables with data stored in Amazon S3.

Follow these steps in order:

  1. Create an external volume for S3: First, create an external volume that points to your S3 bucket where Iceberg table data is stored. Follow the instructions in Create External Volume(s) for the Iceberg Tables on S3.
  2. Create a database: Create a database to organize your tables. Refer to the Snowflake database creation documentation.
  3. Create a schema: Create a schema within your database following the Snowflake schema creation guide.
  4. Create an Iceberg table: Create your Iceberg table using the external volume. Follow the instructions to Create Iceberg Table.

After completing these steps, your Snowflake-managed Iceberg tables are ready to federate with AWS Glue Data Catalog.

Configure access control and authentication

To enable AWS Glue to access your Snowflake-managed Iceberg tables, you need to configure access control and obtain authentication credentials.

Step 1: Configure access control

Create a dedicated Snowflake role for external engine access to establish clear governance boundaries. Follow the instructions in Configure Access Control for external engines and set up the appropriate permissions for your Iceberg tables.

Step 2: Obtain an access token

Generate an access token for authenticating AWS Glue to Snowflake Horizon Catalog. Snowflake supports three authentication mechanisms:

  • External OAuth
  • Key-pair authentication
  • Programmatic Access Token (PAT)

Choose the authentication method that best fits your security requirements and follow the corresponding Snowflake documentation to generate your credentials.

Catalog Federation supports OAuth or custom authentication. For details on using OAuth refer to Federate to Snowflake Iceberg Catalog.

For this post, we use custom authentication and generate access token using PAT. Replace role_name with the principal role and token_value with the principal’s Programmatic Access Token.

curl --location 'https://<accountidentifier>.snowflakecomputing.com/polaris/api/catalog/v1/oauth/tokens' \
--header 'Content-Type: application/x-www-form-urlencoded' \
--data-urlencode 'grant_type=client_credentials' \
--data-urlencode 'scope=session:role:<role_name>' \
--data-urlencode 'client_secret=<token_value>'

Note down the access token that is generated.

Step 3: Enable catalog federation

With access control configured and authentication credentials in hand, AWS Glue Catalog Federation can now connect to and access Snowflake’s Horizon Catalog.

Optional: Snowflake Open Catalog configuration

If you prefer to use Snowflake Open Catalog for Iceberg external access instead, refer to Sync a Snowflake-managed table with Snowflake Open Catalog for alternative setup instructions.

Setup Glue Catalog federation with Snowflake Horizon Catalog

Create a secret on AWS Secrets Manager

Log in to AWS console using the IAM role that has access to AWS Secrets Manager. Open Secrets Manager:

  • Choose Store a new secret and select Other type of secret for the secret type.
  • Set the key-value pair:
    • Key: BEARER_TOKEN
    • Value: The access token noted earlier
  • Choose Next and provide the secret name as horizon-secret.
  • Complete the setup by choosing Store.

Alternatively, you can use the CLI to create the secret by running the following command.

Replace your-access-token and your-region with your actual values:

aws secretsmanager create-secret \
    --name horizon-secret \
    --description "Snowflake Horizon access token" \
    --secret-string '{
        "BEARER_TOKEN": "your-access-token"
    }' \
    --region your-region

Create IAM role for catalog federation

As the catalog owner of a federated catalog in AWS Glue Data Catalog, you can use Lake Formation to implement comprehensive access controls for your data teams:

Access control options

You can implement access controls at different granularity levels depending on your governance needs:

  • Coarse-grained: Table-level permissions
  • Fine-grained: Column-level, row-level, and cell-level filtering
  • Tag-based: Dynamic access based on data classification tags

Lake Formation requires an IAM role with permissions to access the underlying S3 locations of your external catalog.

Create an IAM role that enables the Glue Connection to access AWS Secrets Manager, VPC configurations (optional) and Lake formation to manage credential vending for S3 bucket/prefix.

Required permissions

  1. Secrets Manager access: The Glue connection requires permissions to retrieve secret values from Secrets Manager for OAuth tokens stored for your Snowflake service connection.
  2. Amazon Virtual Private Cloud (VPC) Access (optional): When using VPC endpoints to restrict connectivity to your Snowflake Open Catalog account, the Glue connection needs permissions to describe and use VPC network interfaces. This configuration ensures secure, controlled access to both your stored credentials and network resources while maintaining proper isolation through VPC endpoints.
  3. S3 bucket and AWS Key Management Service (KMS) key permission: The Glue connection requires S3 permissions to read certificates if used in the connection setup. Additionally, Lake Formation requires read permissions on the bucket/prefix where the remote catalog table data resides. If the data is encrypted using a KMS key, additional KMS permissions are required.

Setup steps:

Run the following command using AWS CLI by replacing the placeholder with your setup information:

Create a JSON file (e.g., trust-policy.json) with the following structure:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "Service": ["glue.amazonaws.com","lakeformation.amazonaws.com"]
            },
            "Action": "sts:AssumeRole"
        }
    ]
}

Use the aws iam create-role command, referencing the trust policy file:

aws iam create-role \
    --role-name LFDataAccessRole \
    --assume-role-policy-document file://<path_file_downloaded>/trust-policy.json 

First, create a JSON file (such as, permissions-policy.json) for the permissions:


{
"Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "secretsmanager:GetSecretValue",
                "secretsmanager:DescribeSecret"
            ],
            "Resource": [
                "<secrets manager ARN>"
            ]
        },
        {
            "Effect": "Allow",
            "Action": [
                "ec2:CreateNetworkInterface",
                "ec2:DeleteNetworkInterface",
                "ec2:DescribeNetworkInterfaces"
            ],
            "Resource": "*",
            "Condition": {
                "ArnEquals": {
                    "ec2:Vpc": "arn:aws:ec2:region:account-id:vpc/<vpc-id>", 
                    "ec2:Subnet": [ 
                        "arn:aws:ec2:region:account-id:subnet/<subnet-id>"
                    ]
                }
            }
        },
        {
           # Required when using custom cert to sign requests.
            "Effect": "Allow",
            "Action": [
                "s3:GetObject"
            ],
            "Resource": [
                "arn:aws:s3:::<bucketname>/<certpath>"
            ]
        },
        { # Required when using customer managed encryption key for s3 
            "Effect": "Allow",
            "Action": [
                "kms:decrypt",
                "kms:encrypt"
            ],
            "Resource": [
                "<kmsKey>"
            ]
        }
    ]
}

Then, attach it to the role:

aws iam put-role-policy \
--role-name LFDataAccessRole \
--policy-name myaccesspolicies \
--policy-document file://<path_file_downloaded>/permissions- policy.json

Create federated catalog in Glue Data Catalog

AWS Glue supports the SNOWFLAKEICEBERGRESTCATALOG connection type for connecting Glue Data Catalog with Snowflake Horizon Catalog and Snowflake Open Catalog. This Glue connector supports OAuth2 authentication and includes additional configuration parameters like CASING_TYPE to customize how AWS Glue Data Catalog discovers metadata in the Snowflake Horizon Catalog accounts.

Log in to your AWS console as a data lake admin and open the AWS Lake Formation console.

  1. Choose Catalog in the left navigation pane and select Create catalog.
  2. Choose the data source as Snowflake Horizon Catalog.
    AWS Lake Formation console screenshot showing Step 1 of catalog creation wizard with five federation type options, Snowflake Horizon Catalog selected.
  3. Provide the following information:
    • Name: Name of the federated catalog in Glue Catalog. For this post, we use federated_lakehousedb
    • Catalog name in Snowflake: Catalog name existing in Snowflake Horizon Catalog, this should match exact name in Horizon catalog. For this post, we use LAKEHOUSEDB
    • For Connection details, choose New connection configurations:
      • Connection name: Name for the glue connection. For this post, we use federatedconnection1.
      • Workspace URL: Horizon IRC url (format: https://<account_identifier>.snowflakecomputing.com)
      • Casing type: choose Uppercase only
      • Authentication:
        • Authentication type: choose Custom. Alternatively, you can select OAuth2 authentication. For Custom authentication, an access token is created, refreshed, and managed by the customer’s application or system and stored using AWS Secrets Manager.
        • OAuth Secret: Provide the secret manager ARN that was created in the previous step.
  • If you have AWS PrivateLink setup and/or a proxy setup, you can provide network details under Settings for network configurations (optional).
  • For Register Glue connection with Lake Formation:
    • Choose the IAM role created earlier(LFDataAccessRole) to manage data access using Lake Formation.

To test the connection, choose Run test. After the connection information is validated, it shows as successful.

Green success banner displaying "Connection test successful" with checkmark icon, confirming valid AWS configuration.

You can now create the catalog by selecting Create catalog.

Alternatively, you can use AWS CLI to create connection and catalog using example commands:

aws glue create-connection \
--connection-input '{
"Name": "federatedconnection1",
"ConnectionType": "SNOWFLAKEICEBERGRESTCATALOG",
"ConnectionProperties": {
    "INSTANCE_URL": "<your-snowflake-account-URL>",
    "ROLE_ARN": "< ARN_of_LFDataAccessRole>",
    "CATALOG_CASING_FILTER": "UPPERCASE_ONLY"
},
"AuthenticationConfiguration": {
    "AuthenticationType": "CUSTOM",
    "SecretArn": "arn:aws:secretsmanager:<your-aws-region>:<your-aws-account-id>:secret:horizon-secret"
}
}' \
--region <your-aws-region>
aws lakeformation register-resource \
    --resource-arn <ARN_of_federatedconnection1_connection> \
    --role-arn <ARN_of_LFDataAccessRole> \
    --with-federation \
    --with-privileged-access \
    --region <your-aws-region>
aws glue create-catalog \
    --name federated_lakehousedb \
    --catalog-input '{
    "FederatedCatalog": {
        "Identifier": "LAKEHOUSEDB",
        "ConnectionName": “federatedconnection1 "
    },
    "CreateTableDefaultPermissions": [],
    "CreateDatabaseDefaultPermissions": []
}'

After the catalog is created, the Horizon databases and tables are listed under the federated catalog.

You can implement fine grained access control on the tables by applying row/column filter using Lake Formation.

Query the data using Athena query editor:

Open the Amazon Athena console and run the following query to access the federated Horizon table:

SELECT * FROM "public"."customer" limit 10;

Clean up

To clean up your resources, complete the following steps:

  1. Drop the Snowflake Database with Cascade.
  2. Drop External Volume created for Iceberg Tables on S3.
  3. Drop the resources in Glue Data Catalog and Lake Formation created for this post.
  4. Delete the IAM roles and S3 buckets used for this post.
  5. Delete any VPC, KMS keys if used for this post setup.

Conclusion

In this post, we demonstrated how to establish a secure connection between AWS Analytics services and Snowflake Horizon Catalog, enabling you to access your data from a single connected and governed view. You learned how to:

  • Configure catalog federation between AWS Glue Data Catalog and Snowflake Horizon Catalog
  • Set up OAuth2 authentication for secure access
  • Grant access to Iceberg table in Snowflake Horizon Catalog using AWS Lake Formation
  • Query federated tables using Amazon Athena

You can follow the same steps to establish a secure connection with open-source catalog options such as Snowflake Open Catalog, a managed service for Apache Iceberg. Remember to clean up any resources you created while following this tutorial to avoid ongoing charges.

To further explore this solution in your environment, consider the following resources:

These resources can help you to implement and optimize this integration pattern for your specific use case. As you begin this journey, remember to start small, validate your architecture with test data, and gradually scale your implementation based on your organization’s needs. Stay tuned for future workshops and resources.


About the authors


Andries Engelbrecht

Andries Engelbrecht

Andries is a Principal Partner Solutions Engineer at Snowflake working with AWS. He supports product and service integrations, as well the development of joint solutions with AWS. Andries has over 25 years of experience in the field of data and analytics.

Nidhi Gupta

Nidhi Gupta

Nidhi is a Senior Partner Solutions Architect at AWS, specializing in data analytics and AI. She helps customers and partners build and optimize Snowflake workloads on AWS. Nidhi has extensive experience leading development, production releases and deployments, with focus on Data, AI, ML, generative AI, and Advanced Analytics.

Srividya Parthasarathy

Srividya Parthasarathy

Srividya is a Senior Big Data Architect on the AWS Lake Formation team. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.

Pratik Das

Pratik Das

Pratik is a Senior Product Manager with AWS Lake Formation. He is passionate about all things data and works with customers to understand their requirements and build delightful experiences. He has a background in building data-driven solutions and machine learning systems.


Access Databricks Unity Catalog data using catalog federation in the AWS Glue Data Catalog

Post Syndicated from Srividya Parthasarathy original https://aws.amazon.com/blogs/big-data/access-databricks-unity-catalog-data-using-catalog-federation-in-the-aws-glue-data-catalog/

AWS has launched the catalog federation capability, enabling direct access to Apache Iceberg tables managed in Databricks Unity Catalog through the AWS Glue Data Catalog. With this integration, you can discover and query Unity Catalog data in Iceberg format using an Iceberg REST API endpoint, while maintaining granular access controls through AWS Lake Formation. This approach significantly reduces operational overhead for managing catalog synchronization and associated costs by alleviating the need to replicate or duplicate datasets between platforms.

In this post, we demonstrate how to set up catalog federation between the Glue Data Catalog and Databricks Unity Catalog, enabling data querying using AWS analytics services.

Use cases and key benefits

This federation capability is particularly valuable if you run multiple data platforms, because you can maintain your existing Iceberg catalog investments while using AWS analytics services. Catalog federation supports read operations and provides the following benefits:

  • Interoperability – You can enable interoperability across different data platforms and tools through Iceberg REST APIs while preserving the value of your established technology investments.
  • Cross-platform analytics – You can connect AWS analytics tools (Amazon Athena, Amazon Redshift, Apache Spark) to query Iceberg and UniForm tables stored in Databricks Unity Catalog. It supports Databricks on AWS integration with the AWS Glue Iceberg REST Catalog for metadata retrieval, while using Lake Formation for permission management.
  • Metadata management – The solution avoids manual catalog synchronization by making Databricks Unity Catalog databases and tables discoverable within the Data Catalog. You can implement unified governance through Lake Formation for fine-grained access control across federated catalog resources.

Solution overview

The solution uses catalog federation in the Data Catalog to integrate with Databricks Unity Catalog. The federated catalog created in AWS Glue mirrors the catalog objects in Databricks Unity Catalog and supports OAuth-based authentication. The solution is represented in the following diagram.

The integration involves three high-level steps:

  1. Set up an integration principal in Databricks Unity Catalog and provide required read access on catalog resources to this principal. Enable OAuth-based authentication for the integration principal.
  2. Set up catalog federation to Databricks Unity Catalog in the Glue Data Catalog:
    1. Create a federated catalog in the Data Catalog using an AWS Glue connection.
    2. Create an AWS Glue connection that uses the credentials of the integration principal (in Step 1) to connect to Databricks Unity Catalog. Configure an AWS Identity and Access Management (IAM) role with permission to Amazon Simple Storage Service (Amazon S3) locations where the Iceberg table data resides. In a cross-account scenario, make sure the bucket policy grants required access to this IAM role.
  3. Discover Iceberg tables in federated catalogs using Lake Formation or AWS Glue APIs. During query operations, Lake Formation manages fine-grained permissions on federated resources and credential vending for access to the underlying data.

In the following sections, we walk through the steps to integrate the Glue Data Catalog with Databricks Unity Catalog on AWS.

Prerequisites

To follow along with the solution presented in this post, you must have the following prerequisites:

  • Databricks Workspace (on AWS) with Databricks Unity Catalog configured.
  • An IAM role that is a Lake Formation data lake administrator in your AWS account. A data lake administrator is an IAM principal that can register S3 locations, access the Data Catalog, grant Lake Formation permissions to other users, and view AWS CloudTrail logs. See Create a data lake administrator for more information.

Configure Databricks Unity Catalog for external access

Catalog federation to a Databricks Unity Catalog uses the OAuth2 credentials of a Databricks service principal configured in the workspace admin settings. This authentication mechanism allows the Data Catalog to access the metadata of various objects (such as catalogs, databases, and tables) within Databricks Unity Catalog, based on the privileges associated with the service principal. For proper functionality, grant the service principal with the necessary permissions (read permission on catalog, schema, and tables) to read the metadata of these objects and allow access from external engines.

Next, catalog federation enables discovery and query of Iceberg tables in your Databricks Unity Catalog. For reading delta tables, enable UniForm on a Delta Lake table in Databricks to generate Iceberg metadata. For more information, refer to Read Delta tables with Iceberg clients.

Follow the Databricks tutorial and documentation to create the service principal and associated privileges in your Databricks workspace. For this post, we use a service principal named integrationprincipal that is configured with required permissions (SELECT, USE CATALOG, USE SCHEMA) on Databricks Unity Catalog objects and will be used for authentication to catalog instance.

Catalog federation supports OAuth2 authentication, so enable OAuth for the service principal and note down the client_id and client_secret for later use.

Set up Data Catalog federation with Databricks Unity Catalog

Now that you have service principal access for Databricks Unity Catalog, you can set up catalog federation in the Data Catalog. To do so, you create an AWS Secrets Manager secret and create an IAM role for catalog federation.

Create secret

Complete the following steps to create a secret:

  1. Sign in to the AWS Management Console using an IAM role with access to Secrets Manager.
  2. On the Secrets Manager console, choose Store a new secret and Other type of secret.
  3. Set the key-value pair:
    1. Key: USER_MANAGED_CLIENT_APPLICATION_CLIENT_SECRET
    2. Value: The client secret noted earlier
  4. Choose Next.
  5. Enter a name for your secret (for this post, we use dbx).
  6. Choose Store.

Create IAM role for catalog federation

As the catalog owner of a federated catalog in the Data Catalog, you can use Lake Formation to implement comprehensive access controls, including table filters, column filters, and row filters, as well as tag-based access for your data teams.

Lake Formation requires an IAM role with permissions to access the underlying S3 locations of your external catalog.

In this step, you create an IAM role that enables the AWS Glue connection to access Secrets Manager, optional virtual private cloud (VPC) configurations, and Lake Formation to manage credential vending for the S3 bucket and prefix:

  • Secrets Manager access – The AWS Glue connection requires permissions to retrieve secret values from Secrets Manager for OAuth tokens stored for your Databricks Unity service connection.
  • VPC access (optional) – When using VPC endpoints to restrict connectivity to your Databricks Unity account, the AWS Glue connection needs permissions to describe and utilize VPC network interfaces. This configuration provides secure, controlled access to both your stored credentials and network resources while maintaining proper isolation through VPC endpoints.
  • S3 bucket and AWS KMS key permission – The AWS Glue connection requires Amazon S3 permissions to read certificates if used in the connection setup. Additionally, Lake Formation requires read permissions on the bucket and prefix where the remote catalog table data resides. If the data is encrypted using an AWS Key Management Service (AWS KMS) key, additional AWS KMS permissions are required.

Complete the following steps:

  1. Create an IAM role called LFDataAccessRole with the following policies:
    {
     "Version": "2012-10-17",
         "Statement": [
             {
                 "Effect": "Allow",
                 "Action": [
                     "secretsmanager:GetSecretValue",
                     "secretsmanager:DescribeSecret"
                 ],
                 "Resource": [
                     "<secrets manager ARN>"
                 ]
             },
             {
                 "Effect": "Allow",
                 "Action": [
                     "ec2:CreateNetworkInterface",
                     "ec2:DeleteNetworkInterface",
                     "ec2:DescribeNetworkInterfaces"
                 ],
                 "Resource": "*",
                 "Condition": {
                     "ArnEquals": {
                         "ec2:Vpc": "arn:aws:ec2:region:account-id:vpc/<vpc-id>", 
                         "ec2:Subnet": [ 
                             "arn:aws:ec2:region:account-id:subnet/<subnet-id>" 
                         ]
                     }
                 }
             },
             {
                # Required when using custom cert to sign requests.
                 "Effect": "Allow",
                 "Action": [
                     "s3:GetObject"
                 ],
                 "Resource": [
                     "arn:aws:s3
    :::<bucketname>/<certpath>"
                 ]
             },
             { # Required when using customer managed encryption key for s3 
                 "Effect": "Allow",
                 "Action": [
                     "kms:decrypt",
                     "kms:encrypt"
                 ],
                 "Resource": [
                     "<kmsKey>"
                 ]
             }
         ]
     }

  2. Configure the role with the following trust policy:
    {
          "Version": "2012-10-17",
          "Statement": [
              {
                  "Effect":  "Allow",
                  "Principal": {
                       "Service": ["glue.amazonaws.com","lakeformation.amazonaws.com"]
                  },
                  "Action":  "sts:AssumeRole"
              }
          ]
      }

Create federated catalog in Data Catalog

AWS Glue supports the DATABRICKSICEBERGRESTCATALOG connection type for connecting the Data Catalog with managed Databricks Unity Catalog. This AWS Glue connector supports OAuth2 authentication for discovering metadata in Databricks Unity Catalog.

Complete the following steps to create the federated catalog:

  1. Sign in to the console as a data lake admin.
  2. On the Lake Formation console, choose Catalogs in the navigation pane.
  3. Choose Create catalog.
  4. For Name, enter a name for your catalog.
  5. For Catalog name in Databricks, enter the name of a catalog existing in Databricks Unity Catalog.
  6. For Connection name, enter a name for the AWS Glue connection.
  7. For Workspace URL, enter the Unity Iceberg REST API URL (in format https://<workspace-url>/cloud.databricks.com).
  8. For Authentication, provide the following information:
    1. For Authentication type, choose OAuth2. Alternatively, you can choose Custom authentication. For Custom authentication, an access token is created, refreshed, and managed by the customer’s application or system and stored using Secrets Manager.
    2. For Token URL, enter the token authentication server URL.
    3. For OAuth Client ID, enter the client_id for integrationprincipal.
    4. For OAuth Secret, enter the secret ARN that you created in the previous step. Alternatively, you can provide the client_secret directly.
    5. For Token URL parameter map scope, provide the API scope supported.
  9. If you have AWS PrivateLink set up or a proxy set up, you can provide network details under Settings for network configurations.
  10. For Register Glue connection with Lake Formation, choose the IAM role (LFDataAccessRole) created earlier to manage data access using Lake Formation.

When the setup is done using AWS Command Line Interface (AWS CLI) commands, you have options to create two separate IAM roles:

  • IAM role with policies to access network and secrets, which AWS Glue assumes to manage authentication
  • IAM role with access to the S3 bucket, which Lake Formation assumes to manage credential vending for data access

On the console, this setup is simplified with a single role having combined policies. For more details, refer to Federate to Databricks Unity Catalog.

  1. To test the connection, choose Run test.
  2. You can proceed to create the catalog.

After you create the catalog, you can see the databases and tables in Databricks Unity Catalog listed under the federated catalog. You can implement fine-grained access control on the tables by applying row and column filters using Lake Formation. The following video shows the catalog federation setup with Databricks Unity Catalog.

Discover and query the data using Athena

In this post, we show how to use the Athena query editor to discover and query the Databricks Unity Catalog tables. On the Athena console, run the following query to access the federated table:SELECT * FROM "customerschema"."person" limit 10;The following video demonstrates querying the federated table from Athena.

If you use the Amazon Redshift query engine, you must create a resource link on the federated database and grant permission on the resource link to the user or role. This database resource link is automounted under awsdatacatalog based on the permission granted for the user or role and available for querying. For instructions, refer to Creating resource links.

Clean up

To clean up your resources, complete the following steps:

  1. Delete the catalog and namespace in Databricks Unity Catalog for this post.
  2. Drop the resources in the Data Catalog and Lake Formation created for this post.
  3. Delete the IAM roles and S3 buckets used for this post.
  4. Delete any VPC and KMS keys if used for this post.

Conclusion

In this post, we explored the key elements of catalog federation and its architectural design, illustrating the interaction between the AWS Glue Data Catalog and Databricks Unity Catalog through centralized authorization and credential distribution for protected data access. By removing the requirement for complicated synchronization workflows, catalog federation makes it possible to query Iceberg data on Amazon S3 directly at its source using AWS analytics services with data governance across multi-catalog platforms. Try out the solution for your own use case, and share your feedback and questions in the comments.


About the Authors

Srividya Parthasarathy

Srividya Parthasarathy

Srividya is a Senior Big Data Architect on the AWS Lake Formation team. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.

Venkatavaradhan (Venkat) Viswanathan

Venkatavaradhan (Venkat) Viswanathan

Venkat” is a Global Partner Solutions Architect at Amazon Web Services. Venkat is a Technology Strategy Leader in Data, AI, ML, Generative AI, and Advanced Analytics. Venkat is a Global SME for Databricks and helps AWS customers design, build, secure, and optimize Databricks workloads on AWS.

Create AWS Glue Data Catalog views using cross-account definer roles

Post Syndicated from Aarthi Srinivasan original https://aws.amazon.com/blogs/big-data/create-aws-glue-data-catalog-views-using-cross-account-definer-roles/

With AWS Glue Data Catalog views you can create a SQL view in the Data Catalog that references one or more base tables. These multi-dialect views support various SQL query engines, providing consistent access across multiple Amazon Web Services (AWS) services including Amazon Athena, Amazon Redshift Spectrum, and Apache Spark in both Amazon EMR and AWS Glue 5.0.

You can now create Data Catalog views using a cross-account AWS Identity and Access Management (IAM) definer role. A definer role is an IAM role used to create the Data Catalog view and has SELECT permissions on all columns of the underlying base tables. This definer role is assumed by AWS Glue and AWS Lake Formation service principals to vend credentials to the base tables’ data whenever the view is queried. The definer role allows the Data Catalog view to be shared to principals or AWS accounts so that you can share a filtered subset of data without sharing the base tables.

Previously, Data Catalog views required a definer role within the same AWS account as the base tables. The introduction of cross-account definer roles enables Data Catalog view creation in enterprise data mesh architectures. In this setup, database and table metadata is centralized in a governance account, and individual data owner accounts maintain control over table creation and management through their IAM roles. Data owner accounts can now create and manage Data Catalog views in the central governance accounts using their existing continuous integration and continuous delivery (CI/CD) pipeline roles.

In this post, we show you a cross-account scenario involving two AWS accounts: a central governance account containing the tables and hosting the views and a data owner (producer) account with the IAM role used to create and manage views. We provide implementation details for both SPARK dialect using AWS SDK code samples and ATHENA dialect using SQL commands. Using this approach, you can implement sophisticated data governance models at enterprise scale while maintaining operational efficiency across your AWS environment.

Key benefits

Key benefits for cross-account definer roles are as follows:

  • Enhanced data mesh support – Enterprises with multi-account data lakehouse architectures can now maintain their existing operational model where data owner accounts manage table creation and updates using their established IAM roles. These same roles can now create and manage Data Catalog views across account boundaries.
  • Strengthened security controls – By keeping table and view management within data owner account roles:
    • Security posture is enhanced through proper separation of duties.
    • Audit trails become more comprehensive and meaningful.
    • Access controls follow the principle of least privilege.
  • Elimination of data duplication – Data owner accounts can create views in central accounts that:
    • Provide access to specific data subsets without duplicating tables.
    • Reduce storage costs and management overhead.
    • Maintain a single source of truth while enabling targeted data sharing.

Solution overview

An example customer has a database with two transaction tables in their central account, where the catalog and permissions are maintained. With the database shared to the data owner (producer) account, we create a Data Catalog view in the central account on these two tables, using the producer’s definer role. The view from the central account can be shared to additional consumer accounts and queried. We illustrate creating the SPARK dialect using create-table CLI, and add the ATHENA dialect for the same view from the Athena console. We also provide the AWS SDK sample code for CreateTable() and UpdateTable(), with view definition and a sample pySpark script to read and verify the view in AWS Glue.

The following diagram shows the table, view, and definer IAM role placements between a central governance account and data producer account.

Prerequisites

To perform this solution, you need to have the following prerequisites:

  1. Two AWS accounts with AWS Lake Formation set up. For details, refer to Set up AWS Lake Formation. The Lake Formation setup includes registering your IAM admin role as Lake Formation administrator. In the Data Catalog settings, shown in the following screenshot, Default permissions for newly created databases and tables is set to use Lake Formation permissions only. Cross-account version settings is set to Version 4.

  1. Create an IAM role Data-Analyst in the producer account. For the IAM permissions on this role, refer to Data analyst permissions. This role will also be used as the view definer role. Add the permissions to this definer role from the Prerequisites for creating views.

Create database and tables in the central account

In this step, you create two tables in the central governance account and populate them with few rows of data:

  1. Sign in to the central account as admin user. Open the Athena console and set up the Athena query results bucket.
  2. Run the following queries to create two sample Iceberg tables, representing bank customer transactions data:
/* Check if the Database exists, if not create new database. */
CREATE DATABASE IF NOT EXISTS bankdata_icebergdb;

/*Create transaction_table1*/ Replace the bucket name
CREATE TABLE bankdata_icebergdb.transaction_table1 (
  transaction_id string,
  transaction_type string,
  transaction_amount double)
LOCATION 's3://<bucket-name>/bankdata_icebergdb/transaction-table1'
TBLPROPERTIES (
  'table_type'='iceberg',
  'write_compression'='zstd'
);

/*Create transaction_table2*/
CREATE TABLE bankdata_icebergdb.transaction_table2 (
  transaction_id string,
  transaction_location string,
  transaction_date date)
LOCATION 's3://<bucket-name>/bankdata_icebergdb/transaction-table2'
TBLPROPERTIES (
  'table_type'='iceberg',
  'write_compression'='zstd'
);


INSERT INTO bankdata_icebergdb.transaction_table1 (transaction_id, transaction_type, transaction_amount)
VALUES
  ('T001', 'purchase', 50.0),
  ('T002', 'purchase', 120.0),
  ('T003', 'refund', 200.5),
  ('T004', 'purchase', 80.0),
  ('T005', 'withdrawal', 500.0),
  ('T006', 'purchase', 300.0),
  ('T007', 'deposit', 1000.0),
  ('T008', 'refund', 20.0),
  ('T009', 'purchase', 150.0),
  ('T010', 'withdrawal', 75.0);


INSERT INTO bankdata_icebergdb.transaction_table2 (transaction_id, transaction_location, transaction_date)
VALUES
  ('T001', 'Charlotte', DATE '2024-10-01'),
  ('T002', 'Seattle', DATE '2024-10-02'),
  ('T003', 'Chicago', DATE '2024-10-03'),
  ('T004', 'Miami', DATE '2024-10-04'),
  ('T005', 'New York', DATE '2024-10-05'),
  ('T006', 'Austin', DATE '2024-10-06'),
  ('T007', 'Denver', DATE '2024-10-07'),
  ('T008', 'Boston', DATE '2024-10-08'),
  ('T009', 'San Jose', DATE '2024-10-09'),
  ('T010', 'Phoenix', DATE '2024-10-10');
  1. Verify the created tables in Athena query editor by running a preview.

Share the database and tables from central to producer account

In the central governance account, you share the database and the two tables to the producer account and the Data-Analyst role in producer.

  1. Sign in to the Lake Formation console as the Lake Formation admin role.
  2. In the navigation pane, choose Data permissions.
  3. Choose Grant and provide the following information:
    1. For Principals, select External accounts and enter the producer account ID, as shown in the following screenshot.
    2. For Named Data Catalog Resources, select the default catalog and database bankdata_icebergdb, as shown in the following screenshot.
    3. Under Database permissions, select Describe. For Grantable permissions, select Describe.
    4. Choose Grant.
    5. Repeat the preceding steps to grant access to the producer account definer role Data-Analyst on the database bankdata_icebergdb and the two tables transaction_table1 and transaction_table2 as follows.
    6. Under Database permissions, grant Create table and Describe permissions.
    7. Under Table permissions, grant Select and Describe on all columns.

With these steps, the central governance account data admin steward has shared the database and tables to the producer account definer role.

Steps for producer account

Follow these steps for the producer account:

  1. Sign in to the Lake Formation console on the producer account as the Lake Formation administrator.
  2. In the left navigation pane, choose Databases. A blue banner will appear on the console, showing pending invitations from AWS Resource Access Manager (AWS RAM).
  3. Open the AWS RAM console and review the AWS RAM shares under Shared with me. You will see the AWS RAM shares in pending state. Select the pending AWS RAM share from central account and choose Accept resource share. After the resource share request is accepted, the shared database shows up in the producer account.
  4. On the Lake Formation console, select the database. On the Create dropdown list, choose Resource link. Provide a name rl_bank_iceberg and choose Create.
  5. Let’s grant Describe permission on the resource link to the Data-Analyst role in the producer account in the following steps.
    1. In the left navigation pane, choose Data permissions. Choose the Data-Analyst role. Select the resource link rl_bank_iceberg for the database as shown in the following screenshot.
    2. Grant Describe permission on the resource link.

Note: Cross-account Data Catalog views can’t be created using a resource link, although a resource link is needed for the SDK use of SPARK dialect.

Next, add the central account Data Catalog as a Data Source in Athena from producer account:

  1. Open the Athena console.
  2. On the left navigation pane, choose Data sources and catalogs. Choose Create data source.
    1. Select S3-AWS Glue Data Catalog.
    2. Choose AWS – Glue Data Catalog in another account and name the data source as centraladmin.
    3. Choose Next and then create data source.

After the data source is created, navigate to the Query editor and verify the Data source centraladmin appears, as shown in the following screenshot.

The definer role can also now access and query the central catalog database.

Create SPARK dialect view

In this step, you create a view with SPARK dialect, using AWS Glue CLI command create-table:

  1. Sign in to the AWS console in the producer account as Data-Analyst role. Enter the following command in your CLI environment, such as AWS CloudShell, to create a SPARK DIALECT:
aws glue create-table --cli-input-json '{
   "DatabaseName": "rl_bank_iceberg",
   "TableInput": {
     "Name": "mdv_transaction1",
     "StorageDescriptor": {
       "Columns": [
         {
           "Name": "transaction_id",
           "Type": "string"
         },
         {
           "Name": "transaction_type",
           "Type": "string"
         },
         {
           "Name": "transaction_amount",
           "Type": "float"
         },
         {
           "Name": "transaction_location",
           "Type": "string"
         },
         {
           "Name": "transaction_date",
           "Type": "date"
         }
       ],
       "SerdeInfo": {}
     },
     "ViewDefinition": {
       "SubObjects": [
         "arn:aws:glue:<your-region>:<your-central-account-id>:table/bankdata_icebergdb/transaction_table1",
         "arn:aws:glue:<your-region>:<your-central-account-id>:table/bankdata_icebergdb/transaction_table2"
        ],
       "IsProtected": true,
       "Representations": [
         {
           "Dialect": "SPARK",
           "DialectVersion": "1.0",
           "ViewOriginalText": "SELECT t1.transaction_id, t1.transaction_type, t1.transaction_amount, t2.transaction_location, t2.transaction_date FROM transaction_table1 t1 JOIN transaction_table2 t2 ON t1.transaction_id = t2.transaction_id WHERE t1.transaction_amount > 100;",
           "ViewExpandedText": "SELECT t1.transaction_id, t1.transaction_type, t1.transaction_amount, t2.transaction_location, t2.transaction_date FROM transaction_table1 t1 JOIN transaction_table2 t2 ON t1.transaction_id = t2.transaction_id WHERE t1.transaction_amount > 100;"
         }
       ]
     }
   }
 }'
  1. Open the Lake Formation console and verify if the view is created. Verify the dialect of the view on the SQL definitions tab for the view details.

Add ATHENA dialect

To add ATHENA dialect, follow these steps:

  1. On the Athena console, select centraladmin from the Data source.
  2. Enter the following SQL script to create the ATHENA dialect for the same view:
ALTER VIEW mdv_transaction1 FORCE ADD DIALECT
AS
SELECT t1.transaction_id, t1.transaction_type, t1.transaction_amount, t2.transaction_location, t2.transaction_date FROM transaction_table1 t1 JOIN transaction_table2 t2 ON t1.transaction_id = t2.transaction_id WHERE t1.transaction_amount > 100

We can’t use the resource link rl_bank_iceberg in the Athena query editor to create or alter a view in the central account.

  1. Verify the added dialect by running a preview in Athena. For running the query, you can use either the resource link rl_bank_iceberg from the producer account catalog or use the centraladmin catalog.

The following screenshot shows querying using the resource link of the database in the producer account catalog.

The following screenshot shows querying the view from the producer using the connected catalog centraladmin as the data source.

  1. Verify the dialects on the view by inspecting the table in the Lake Formation console.

You can now query the view as the Data-Analyst role in the producer account, using both Athena and Spark. The view will also show in the central account as shown in the following code example, with access to the Lake Formation admin.

You can also create the view with ATHENA dialect and add the SPARK dialect. The SQL syntax to create the view in ATHENA dialect is shown in the following example:

create protected multi dialect view mdv_transaction1
security definer
as
SELECT t1.transaction_id, t1.transaction_type, t1.transaction_amount, t2.transaction_location, t2.transaction_date FROM transaction_table1 t1 
JOIN transaction_table2 t2 
ON t1.transaction_id = t2.transaction_id 
WHERE t1.transaction_amount > 100;

The update-table CLI to add the corresponding SPARK dialect is shown in the following example:

aws glue update-table --cli-input-json '{
    "DatabaseName": "rl_bankdatadb",
    "ViewUpdateAction": "ADD",
    "Force": true,
    "TableInput": {
        "Name": " mdv_transaction1",
        "StorageDescriptor": {
            "Columns": [
                {
                  "Name": "transaction_id",
                  "Type": "string"
                },
                {
                  "Name": "transaction_type",
                  "Type": "string"
                },
                {
                  "Name": "transaction_amount",
                  "Type": "float"
                },
                {
                  "Name": "transaction_location",
                  "Type": "string"
                },
                {
                  "Name": "transaction_date",
                  "Type": "date"
                }
             ],
             "SerdeInfo": {}
         },
         "ViewDefinition": {
         "SubObjects": [
               " "arn:aws:glue:<your-region>:<your-central-account-id>:table/bankdata_icebergdb/transaction_table1",
           "arn:aws:glue:<your-region>:<your-central-account-id>:table/bankdata_icebergdb/transaction_table2" 
],
         "IsProtected": true,
         "Representations": [
             {
                 "Dialect": "SPARK",
                 "DialectVersion": "1.0",
                 "ViewOriginalText": " SELECT t1.transaction_id, t1.transaction_type, t1.transaction_amount, t2.transaction_location, t2.transaction_date FROM transaction_table1 t1 JOIN transaction_table2 t2 ON t1.transaction_id = t2.transaction_id WHERE t1.transaction_amount > 100",
                 "ViewExpandedText": " SELECT t1.transaction_id, t1.transaction_type, t1.transaction_amount, t2.transaction_location, t2.transaction_date FROM transaction_table1 t1 JOIN transaction_table2 t2 ON t1.transaction_id = t2.transaction_id WHERE t1.transaction_amount > 100"
              }
           ]
        }
    }
}'

The following is a sample Python script to create a SPARK dialect view: glueview-createtable.py.

The following code block is a sample AWS Glue extract, transfer, and load (ETL) script to access the Spark dialect of the view from AWS Glue 5.0 from the central account. The AWS Glue job execution role should have Lake Formation SELECT permission on the AWS Glue view:

from pyspark.context import SparkContext
from pyspark.sql import SparkSession

aws_region = "<your-region>"
aws_account_id = "<your-central-account-id>"
local_catalogname = "spark_catalog"
warehouse_path = "s3://<your-bucket-name>/bankdata_icebergdb/transaction-table1"

spark = SparkSession.builder.appName('query_glue_view') \
    .config('spark.sql.extensions','org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions') \
    .config(f'spark.sql.catalog.{local_catalogname}', 'org.apache.iceberg.spark.SparkSessionCatalog') \
    .config(f'spark.sql.catalog.{local_catalogname}.catalog-impl', 'org.apache.iceberg.aws.glue.GlueCatalog') \
    .config(f'spark.sql.catalog.{local_catalogname}.client.region', aws_region) \
    .config(f'spark.sql.catalog.{local_catalogname}.glue.account-id', aws_account_id) \
    .config(f'spark.sql.catalog.{local_catalogname}.io-impl', 'org.apache.iceberg.aws.s3.S3FileIO') \
    .config(f'spark.sql.catalog.{local_catalogname}.warehouse',warehouse_path) \
    .getOrCreate()
spark.sql(f"show databases").show()
spark.sql(f"SHOW TABLES IN {local_catalogname}.bankdata_icebergdb").show()
spark.sql(f"SELECT * FROM {local_catalogname}.bankdata_icebergdb. mdv_transaction1").show()

In the AWS Glue job-details, for Lake Formation managed tables and for Iceberg tables, set additional parameters respectively as follows:

--enable-lakeformation-fine-grained-access = true
--datalake-formats = iceberg

Cleanup

To avoid incurring costs, clean up the resources you used for this post:

  1. Revoke the Lake Formation permissions granted to the Data-Analyst role and Producer account
  2. Drop the Athena tables
  3. Delete the Athena query results from your Amazon Simple Storage Service (Amazon S3) bucket
  4. Delete the Data-Analyst role from IAM

Conclusion

In this post, we demonstrated how to use cross-account IAM definer roles with AWS Glue Data Catalog views. We showed how data owner accounts can create and manage views in a central governance account while maintaining security and control over their data assets. This feature enables enterprises to implement sophisticated data mesh architectures without compromising on security or requiring data duplication.

The ability to use cross-account definer roles with Data Catalog views provides several key advantages:

  • Streamlines view management in multi-account environments
  • Maintains existing CI/CD workflows and automation
  • Enhances security through centralized governance
  • Reduces operational overhead by eliminating the need for data duplication

As organizations continue to build and scale their data lakehouse architectures across multiple AWS accounts, cross-account definer roles for Data Catalog views provide a crucial capability for implementing efficient, secure, and well-governed data sharing patterns.


About the authors

Aarthi Srinivasan

Aarthi Srinivasan

Aarthi is a Senior Big Data Architect at Amazon Web Services (AWS). She works with AWS customers and partners to architect data lake solutions, enhance product features, and establish best practices for data governance.

Sundeep Kumar

Sundeep Kumar

Sundeep is a Sr. Specialist Solutions Architect at Amazon Web Services (AWS), helping customers build data lake and analytics platforms and solutions. When not building and designing data lakes, Sundeep enjoys listening to music and playing guitar.

AWS analytics at re:Invent 2025: Unifying Data, AI, and governance at scale

Post Syndicated from Larry Weber original https://aws.amazon.com/blogs/big-data/aws-analytics-at-reinvent-2025-unifying-data-ai-and-governance-at-scale/

re:Invent 2025 showcased the bold Amazon Web Services (AWS) vision for the future of analytics, one where data warehouses, data lakes, and AI development converge into a seamless, open, intelligent platform, with Apache Iceberg compatibility at its core. Across over 18 major announcements spanning three weeks, AWS demonstrated how organizations can break down data silos, accelerate insights with AI, and maintain robust governance without sacrificing agility.

Amazon SageMaker: Your data platform, simplified

AWS introduced a faster, simpler approach to data platform onboarding for Amazon SageMaker Unified Studio. The new one-click onboarding experience eliminates weeks of setup, so teams can start working with existing datasets in minutes using their current AWS Identity and Access Management (IAM) roles and permissions. Accessible directly from Amazon SageMaker, Amazon Athena, Amazon Redshift, and Amazon S3 Tables consoles, this streamlined experience automatically creates SageMaker Unified Studio projects with existing data permissions intact. At its core is a powerful new serverless notebook that reimagines how data professionals work. This single interface combines SQL queries, Python code, Apache Spark processing, and natural language prompts, backed by Amazon Athena for Apache Spark to scale from interactive exploration to petabyte-scale jobs. Data engineers, analysts, and data scientists no longer need to context-switch between different tools based on workload—they can explore data with SQL, build models with Python, and use AI assistance, all in one place.

The introduction of Amazon SageMaker Data Agent in the new SageMaker notebooks marks a pivotal moment in AI-assisted development for data builders. This built-in agent doesn’t only generate code, it understands your data context, catalog information, and business metadata to create intelligent execution plans from natural language descriptions. When you describe an objective, the agent breaks down complex analytics and machine learning (ML) tasks into manageable steps, generates the required SQL and Python code, and maintains awareness of your notebook environment throughout the entire process. This capability transforms hours of manual coding into minutes of guided development, which means teams can focus on gleaning insights rather than repetitive boilerplate.

Embracing open data with Apache Iceberg

One significant theme across this year’s launches was the widespread adoption of Apache Iceberg across AWS analytics, transforming how organizations manage petabyte-scale data lakes. Catalog federation to remote Iceberg catalogs through the AWS Glue Data Catalog addresses a critical challenge in modern data architectures. You can now query remote Iceberg tables, stored in Amazon Simple Storage Service (Amazon S3) and catalogued in remote Iceberg catalogs, using preferred AWS analytics services such as Amazon Redshift, Amazon EMR, Amazon Athena, AWS Glue, and Amazon SageMaker, without moving or copying tables. Metadata synchronizes in real time, providing query results that reflect the current state. Catalog federation supports both coarse-grained access control and fine-grained access permissions through AWS Lake Formation enabling cross-account sharing and trusted identity propagation while maintaining consistent security across federated catalogs.

Amazon Redshift now writes directly to Apache Iceberg tables, enabling true open lakehouse architectures where analytics seamlessly span data warehouses and lakes. Apache Spark on Amazon EMR 7.12, AWS Glue, Amazon SageMaker notebooks, Amazon S3 Tables, and the AWS Glue Data Catalog now support Iceberg V3’s capabilities, including deletion vectors that mark deleted rows without expensive file rewrites, dramatically reducing pipeline costs and accelerating data modifications and row lineage. V3 automatically tracks every record’s history, creating audit trails essential for compliance and has table-level encryption that helps organizations meet stringent privacy regulations. These innovations mean faster writes, lower storage costs, comprehensive audit trails, and efficient incremental processing across your data architecture.

Governance that scales with your organization

Data governance received substantial attention at re:Invent with major enhancements to Amazon SageMaker Catalog. Organizations can now curate data at the column level with custom metadata forms and rich text descriptions, indexed in real time for immediate discoverability. New metadata enforcement rules require data producers to classify assets with approved business vocabulary before publication, providing consistency across the enterprise. The catalog uses Amazon Bedrock large language models (LLMs) to automatically suggest relevant business glossary terms by analyzing table metadata and schema information, bridging the gap between technical schemas and business language. Perhaps most importantly, SageMaker Catalog now exports its entire asset metadata as queryable Apache Iceberg tables through Amazon S3 Tables. This way, teams can analyze catalog inventory with standard SQL to answer questions like “which assets lack business descriptions?” or “how many confidential datasets were registered last month?” without building custom ETL infrastructure.

As organizations adopt multi-warehouse architectures to scale and isolate workloads, the new Amazon Redshift federated permissions capability eliminates governance complexity. Define data permissions one time from a Amazon Redshift warehouse, and they automatically enforce them across the warehouses in your account. Row-level, column-level, and masking controls apply consistently regardless of which warehouse queries originate from, and new warehouses automatically inherit permission policies. This horizontal scalability means organizations can add warehouses without increasing governance overhead, and analysts immediately see the databases from registered warehouses.

Accelerating AI innovation with Amazon OpenSearch Service

Amazon OpenSearch Service introduced powerful new capabilities to simplify and accelerate AI application development. With support for OpenSearch 3.3, agentic search enables precise results using natural language inputs without the need for complex queries, making it easier to build intelligent AI agents. The new Apache Calcite-powered PPL engine delivers query optimization and an extensive library of commands for more efficient data processing.

As seen in Matt Garman’s keynote, building large-scale vector databases is now dramatically faster with GPU acceleration and auto-optimization. Previously, creating large-scale vector indexes required days of building time and weeks of manual tuning by experts, which slowed innovation and prevented cost-performance optimizations. The new serverless auto-optimize jobs automatically evaluate index configurations—including k-nearest neighbors (k-NN) algorithms, quantization, and engine settings—based on your specified search latency and recall requirements. Combined with GPU acceleration, you can build optimized indexes up to ten times faster at 25% of the indexing cost, with serverless GPUs that activate dynamically and bill only when providing speed boosts. These advancements simplify scaling AI applications such as semantic search, recommendation engines, and agentic systems, so teams can innovate faster by dramatically reducing the time and effort needed to build large-scale, optimized vector databases.

Performance and cost optimization

Also announced in the keynote, Amazon EMR Serverless now eliminates local storage provisioning for Apache Spark workloads, introducing serverless storage that reduces data processing costs by up to 20% while preventing job failures from disk capacity constraints. The fully managed, auto scaling storage encrypts data in transit and at rest with job-level isolation, allowing Spark to release workers immediately when idle rather than keeping them active to preserve temporary data. Additionally, AWS Glue introduced materialized views based on Apache Iceberg, storing precomputed query results that automatically refresh as source data changes. Spark engines across Amazon Athena, Amazon EMR, and AWS Glue intelligently rewrite queries to use these views, accelerating performance by up to eight times while reducing compute costs. The service handles refresh schedules, change detection, incremental updates, and infrastructure management automatically.

The new Apache Spark upgrade agent for Amazon EMR transforms version upgrades from months-long projects into week-long initiatives. Using conversational interfaces, engineers express upgrade requirements in natural language while the agent automatically identifies API changes and behavioral modifications across PySpark and Scala applications. Engineers review and approve suggested changes before implementation, maintaining full control while the agent validates functional correctness through data quality checks. Currently supporting upgrades from Spark 2.4 to 3.5, this capability is available through SageMaker Unified Studio, Kiro CLI, or an integrated development environment (IDE) with Model Context Protocol compatibility.

For workflow optimization, AWS introduced a new Serverless deployment option for Amazon Managed Workflows for Apache Airflow (Amazon MWAA), which eliminates the operational overhead of managing Apache Airflow environments while optimizing costs through serverless scaling. This new offering addresses key challenges of operational scalability, cost optimization, and access management that data engineers and DevOps teams face when orchestrating workflows. With Amazon MWAA Serverless, data engineers can focus on defining their workflow logic rather than monitoring for provisioned capacity. They can now submit their Airflow workflows for execution on a schedule or on demand, paying only for the actual compute time used during each task’s execution.

Looking forward

These launches collectively represent more than incremental improvements. They signal a fundamental shift in how organizations are approaching analytics. By unifying data warehousing, data lakes, and ML under a common framework built on Apache Iceberg, simplifying access through intelligent interfaces powered by AI, and maintaining robust governance that scales effortlessly, AWS is giving organizations the tools to focus on insights rather than infrastructure. The emphasis on automation, from AI-assisted development to self-managing materialized views and serverless storage, reduces operational overhead while improving performance and cost efficiency. As data volumes continue to grow and AI becomes increasingly central to business operations, these capabilities position AWS customers to accelerate their data-driven initiatives with unprecedented simplicity and power. To view the Re:Invent 2025 Innovation Talk on analytics, visit Harnessing analytics for humans and AI on YouTube.


About the authors

Larry Weber

Larry Weber

Larry leads product marketing for the analytics portfolio at AWS.