Tag Archives: AWS Glue

Access Databricks Unity Catalog data using catalog federation in the AWS Glue Data Catalog

Post Syndicated from Srividya Parthasarathy original https://aws.amazon.com/blogs/big-data/access-databricks-unity-catalog-data-using-catalog-federation-in-the-aws-glue-data-catalog/

AWS has launched the catalog federation capability, enabling direct access to Apache Iceberg tables managed in Databricks Unity Catalog through the AWS Glue Data Catalog. With this integration, you can discover and query Unity Catalog data in Iceberg format using an Iceberg REST API endpoint, while maintaining granular access controls through AWS Lake Formation. This approach significantly reduces operational overhead for managing catalog synchronization and associated costs by alleviating the need to replicate or duplicate datasets between platforms.

In this post, we demonstrate how to set up catalog federation between the Glue Data Catalog and Databricks Unity Catalog, enabling data querying using AWS analytics services.

Use cases and key benefits

This federation capability is particularly valuable if you run multiple data platforms, because you can maintain your existing Iceberg catalog investments while using AWS analytics services. Catalog federation supports read operations and provides the following benefits:

  • Interoperability – You can enable interoperability across different data platforms and tools through Iceberg REST APIs while preserving the value of your established technology investments.
  • Cross-platform analytics – You can connect AWS analytics tools (Amazon Athena, Amazon Redshift, Apache Spark) to query Iceberg and UniForm tables stored in Databricks Unity Catalog. It supports Databricks on AWS integration with the AWS Glue Iceberg REST Catalog for metadata retrieval, while using Lake Formation for permission management.
  • Metadata management – The solution avoids manual catalog synchronization by making Databricks Unity Catalog databases and tables discoverable within the Data Catalog. You can implement unified governance through Lake Formation for fine-grained access control across federated catalog resources.

Solution overview

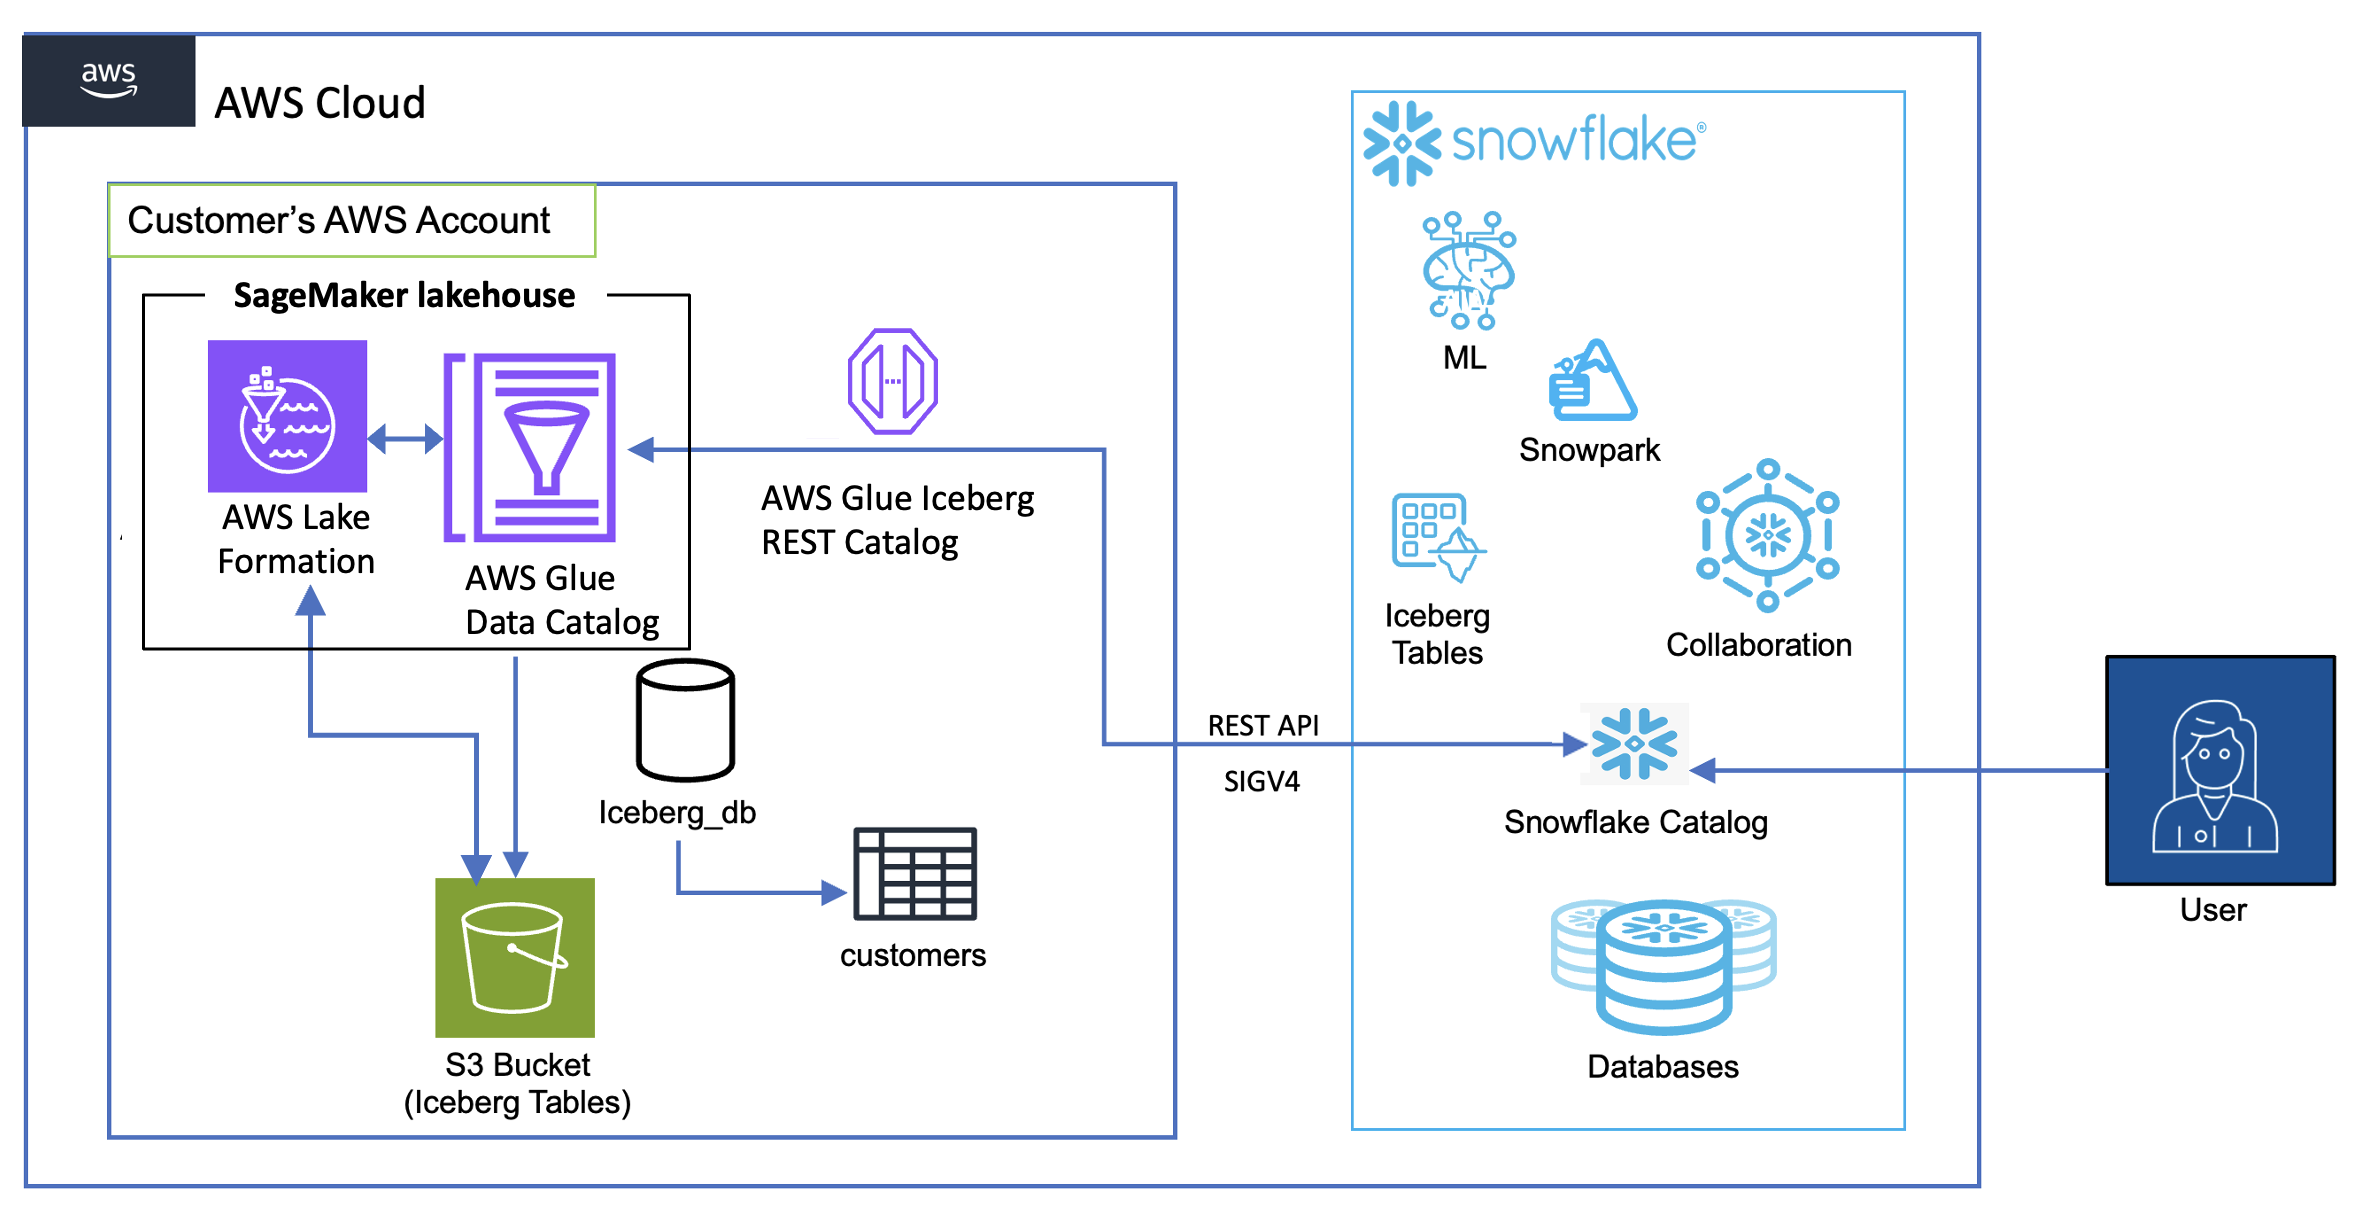
The solution uses catalog federation in the Data Catalog to integrate with Databricks Unity Catalog. The federated catalog created in AWS Glue mirrors the catalog objects in Databricks Unity Catalog and supports OAuth-based authentication. The solution is represented in the following diagram.
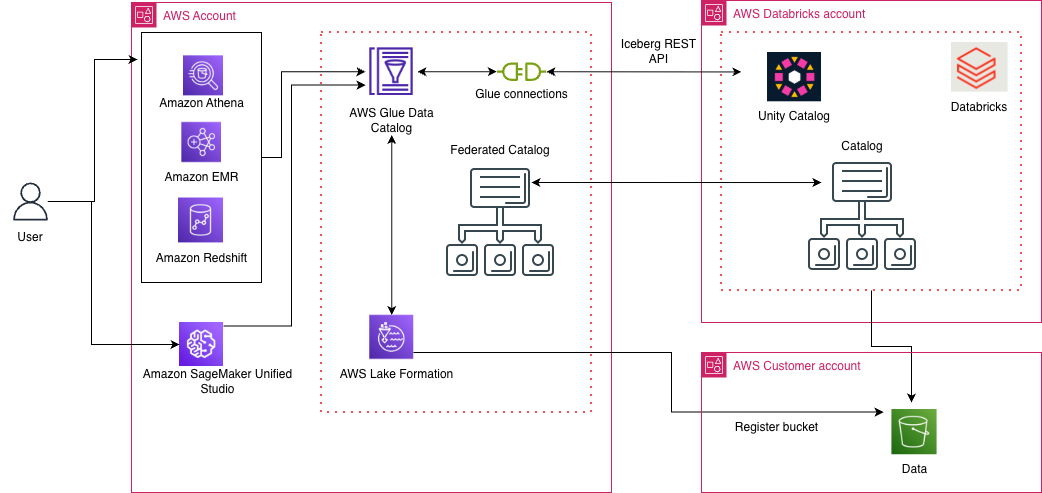
The integration involves three high-level steps:

  1. Set up an integration principal in Databricks Unity Catalog and provide required read access on catalog resources to this principal. Enable OAuth-based authentication for the integration principal.
  2. Set up catalog federation to Databricks Unity Catalog in the Glue Data Catalog:
    1. Create a federated catalog in the Data Catalog using an AWS Glue connection.
    2. Create an AWS Glue connection that uses the credentials of the integration principal (in Step 1) to connect to Databricks Unity Catalog. Configure an AWS Identity and Access Management (IAM) role with permission to Amazon Simple Storage Service (Amazon S3) locations where the Iceberg table data resides. In a cross-account scenario, make sure the bucket policy grants required access to this IAM role.
  3. Discover Iceberg tables in federated catalogs using Lake Formation or AWS Glue APIs. During query operations, Lake Formation manages fine-grained permissions on federated resources and credential vending for access to the underlying data.

In the following sections, we walk through the steps to integrate the Glue Data Catalog with Databricks Unity Catalog on AWS.

Prerequisites

To follow along with the solution presented in this post, you must have the following prerequisites:

  • Databricks Workspace (on AWS) with Databricks Unity Catalog configured.
  • An IAM role that is a Lake Formation data lake administrator in your AWS account. A data lake administrator is an IAM principal that can register S3 locations, access the Data Catalog, grant Lake Formation permissions to other users, and view AWS CloudTrail logs. See Create a data lake administrator for more information.

Configure Databricks Unity Catalog for external access

Catalog federation to a Databricks Unity Catalog uses the OAuth2 credentials of a Databricks service principal configured in the workspace admin settings. This authentication mechanism allows the Data Catalog to access the metadata of various objects (such as catalogs, databases, and tables) within Databricks Unity Catalog, based on the privileges associated with the service principal. For proper functionality, grant the service principal with the necessary permissions (read permission on catalog, schema, and tables) to read the metadata of these objects and allow access from external engines.

Next, catalog federation enables discovery and query of Iceberg tables in your Databricks Unity Catalog. For reading delta tables, enable UniForm on a Delta Lake table in Databricks to generate Iceberg metadata. For more information, refer to Read Delta tables with Iceberg clients.

Follow the Databricks tutorial and documentation to create the service principal and associated privileges in your Databricks workspace. For this post, we use a service principal named integrationprincipal that is configured with required permissions (SELECT, USE CATALOG, USE SCHEMA) on Databricks Unity Catalog objects and will be used for authentication to catalog instance.

Catalog federation supports OAuth2 authentication, so enable OAuth for the service principal and note down the client_id and client_secret for later use.

Set up Data Catalog federation with Databricks Unity Catalog

Now that you have service principal access for Databricks Unity Catalog, you can set up catalog federation in the Data Catalog. To do so, you create an AWS Secrets Manager secret and create an IAM role for catalog federation.

Create secret

Complete the following steps to create a secret:

  1. Sign in to the AWS Management Console using an IAM role with access to Secrets Manager.
  2. On the Secrets Manager console, choose Store a new secret and Other type of secret.
  3. Set the key-value pair:
    1. Key: USER_MANAGED_CLIENT_APPLICATION_CLIENT_SECRET
    2. Value: The client secret noted earlier
  4. Choose Next.
  5. Enter a name for your secret (for this post, we use dbx).
  6. Choose Store.

Create IAM role for catalog federation

As the catalog owner of a federated catalog in the Data Catalog, you can use Lake Formation to implement comprehensive access controls, including table filters, column filters, and row filters, as well as tag-based access for your data teams.

Lake Formation requires an IAM role with permissions to access the underlying S3 locations of your external catalog.

In this step, you create an IAM role that enables the AWS Glue connection to access Secrets Manager, optional virtual private cloud (VPC) configurations, and Lake Formation to manage credential vending for the S3 bucket and prefix:

  • Secrets Manager access – The AWS Glue connection requires permissions to retrieve secret values from Secrets Manager for OAuth tokens stored for your Databricks Unity service connection.
  • VPC access (optional) – When using VPC endpoints to restrict connectivity to your Databricks Unity account, the AWS Glue connection needs permissions to describe and utilize VPC network interfaces. This configuration provides secure, controlled access to both your stored credentials and network resources while maintaining proper isolation through VPC endpoints.
  • S3 bucket and AWS KMS key permission – The AWS Glue connection requires Amazon S3 permissions to read certificates if used in the connection setup. Additionally, Lake Formation requires read permissions on the bucket and prefix where the remote catalog table data resides. If the data is encrypted using an AWS Key Management Service (AWS KMS) key, additional AWS KMS permissions are required.

Complete the following steps:

  1. Create an IAM role called LFDataAccessRole with the following policies:
    {
     "Version": "2012-10-17",
         "Statement": [
             {
                 "Effect": "Allow",
                 "Action": [
                     "secretsmanager:GetSecretValue",
                     "secretsmanager:DescribeSecret"
                 ],
                 "Resource": [
                     "<secrets manager ARN>"
                 ]
             },
             {
                 "Effect": "Allow",
                 "Action": [
                     "ec2:CreateNetworkInterface",
                     "ec2:DeleteNetworkInterface",
                     "ec2:DescribeNetworkInterfaces"
                 ],
                 "Resource": "*",
                 "Condition": {
                     "ArnEquals": {
                         "ec2:Vpc": "arn:aws:ec2:region:account-id:vpc/<vpc-id>", 
                         "ec2:Subnet": [ 
                             "arn:aws:ec2:region:account-id:subnet/<subnet-id>" 
                         ]
                     }
                 }
             },
             {
                # Required when using custom cert to sign requests.
                 "Effect": "Allow",
                 "Action": [
                     "s3:GetObject"
                 ],
                 "Resource": [
                     "arn:aws:s3
    :::<bucketname>/<certpath>"
                 ]
             },
             { # Required when using customer managed encryption key for s3 
                 "Effect": "Allow",
                 "Action": [
                     "kms:decrypt",
                     "kms:encrypt"
                 ],
                 "Resource": [
                     "<kmsKey>"
                 ]
             }
         ]
     }

  2. Configure the role with the following trust policy:
    {
          "Version": "2012-10-17",
          "Statement": [
              {
                  "Effect":  "Allow",
                  "Principal": {
                       "Service": ["glue.amazonaws.com","lakeformation.amazonaws.com"]
                  },
                  "Action":  "sts:AssumeRole"
              }
          ]
      }

Create federated catalog in Data Catalog

AWS Glue supports the DATABRICKSICEBERGRESTCATALOG connection type for connecting the Data Catalog with managed Databricks Unity Catalog. This AWS Glue connector supports OAuth2 authentication for discovering metadata in Databricks Unity Catalog.

Complete the following steps to create the federated catalog:

  1. Sign in to the console as a data lake admin.
  2. On the Lake Formation console, choose Catalogs in the navigation pane.
  3. Choose Create catalog.
  4. For Name, enter a name for your catalog.
  5. For Catalog name in Databricks, enter the name of a catalog existing in Databricks Unity Catalog.
  6. For Connection name, enter a name for the AWS Glue connection.
  7. For Workspace URL, enter the Unity Iceberg REST API URL (in format https://<workspace-url>/cloud.databricks.com).
  8. For Authentication, provide the following information:
    1. For Authentication type, choose OAuth2. Alternatively, you can choose Custom authentication. For Custom authentication, an access token is created, refreshed, and managed by the customer’s application or system and stored using Secrets Manager.
    2. For Token URL, enter the token authentication server URL.
    3. For OAuth Client ID, enter the client_id for integrationprincipal.
    4. For OAuth Secret, enter the secret ARN that you created in the previous step. Alternatively, you can provide the client_secret directly.
    5. For Token URL parameter map scope, provide the API scope supported.
  9. If you have AWS PrivateLink set up or a proxy set up, you can provide network details under Settings for network configurations.
  10. For Register Glue connection with Lake Formation, choose the IAM role (LFDataAccessRole) created earlier to manage data access using Lake Formation.

When the setup is done using AWS Command Line Interface (AWS CLI) commands, you have options to create two separate IAM roles:

  • IAM role with policies to access network and secrets, which AWS Glue assumes to manage authentication
  • IAM role with access to the S3 bucket, which Lake Formation assumes to manage credential vending for data access

On the console, this setup is simplified with a single role having combined policies. For more details, refer to Federate to Databricks Unity Catalog.

  1. To test the connection, choose Run test.
  2. You can proceed to create the catalog.

After you create the catalog, you can see the databases and tables in Databricks Unity Catalog listed under the federated catalog. You can implement fine-grained access control on the tables by applying row and column filters using Lake Formation. The following video shows the catalog federation setup with Databricks Unity Catalog.

Discover and query the data using Athena

In this post, we show how to use the Athena query editor to discover and query the Databricks Unity Catalog tables. On the Athena console, run the following query to access the federated table:SELECT * FROM "customerschema"."person" limit 10;The following video demonstrates querying the federated table from Athena.

If you use the Amazon Redshift query engine, you must create a resource link on the federated database and grant permission on the resource link to the user or role. This database resource link is automounted under awsdatacatalog based on the permission granted for the user or role and available for querying. For instructions, refer to Creating resource links.

Clean up

To clean up your resources, complete the following steps:

  1. Delete the catalog and namespace in Databricks Unity Catalog for this post.
  2. Drop the resources in the Data Catalog and Lake Formation created for this post.
  3. Delete the IAM roles and S3 buckets used for this post.
  4. Delete any VPC and KMS keys if used for this post.

Conclusion

In this post, we explored the key elements of catalog federation and its architectural design, illustrating the interaction between the AWS Glue Data Catalog and Databricks Unity Catalog through centralized authorization and credential distribution for protected data access. By removing the requirement for complicated synchronization workflows, catalog federation makes it possible to query Iceberg data on Amazon S3 directly at its source using AWS analytics services with data governance across multi-catalog platforms. Try out the solution for your own use case, and share your feedback and questions in the comments.
About the Authors

Srividya Parthasarathy

Srividya Parthasarathy

Srividya is a Senior Big Data Architect on the AWS Lake Formation team. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.

Venkatavaradhan (Venkat) Viswanathan

Venkatavaradhan (Venkat) Viswanathan

Venkat” is a Global Partner Solutions Architect at Amazon Web Services. Venkat is a Technology Strategy Leader in Data, AI, ML, Generative AI, and Advanced Analytics. Venkat is a Global SME for Databricks and helps AWS customers design, build, secure, and optimize Databricks workloads on AWS.

Create AWS Glue Data Catalog views using cross-account definer roles

Post Syndicated from Aarthi Srinivasan original https://aws.amazon.com/blogs/big-data/create-aws-glue-data-catalog-views-using-cross-account-definer-roles/

With AWS Glue Data Catalog views you can create a SQL view in the Data Catalog that references one or more base tables. These multi-dialect views support various SQL query engines, providing consistent access across multiple Amazon Web Services (AWS) services including Amazon Athena, Amazon Redshift Spectrum, and Apache Spark in both Amazon EMR and AWS Glue 5.0.

You can now create Data Catalog views using a cross-account AWS Identity and Access Management (IAM) definer role. A definer role is an IAM role used to create the Data Catalog view and has SELECT permissions on all columns of the underlying base tables. This definer role is assumed by AWS Glue and AWS Lake Formation service principals to vend credentials to the base tables’ data whenever the view is queried. The definer role allows the Data Catalog view to be shared to principals or AWS accounts so that you can share a filtered subset of data without sharing the base tables.

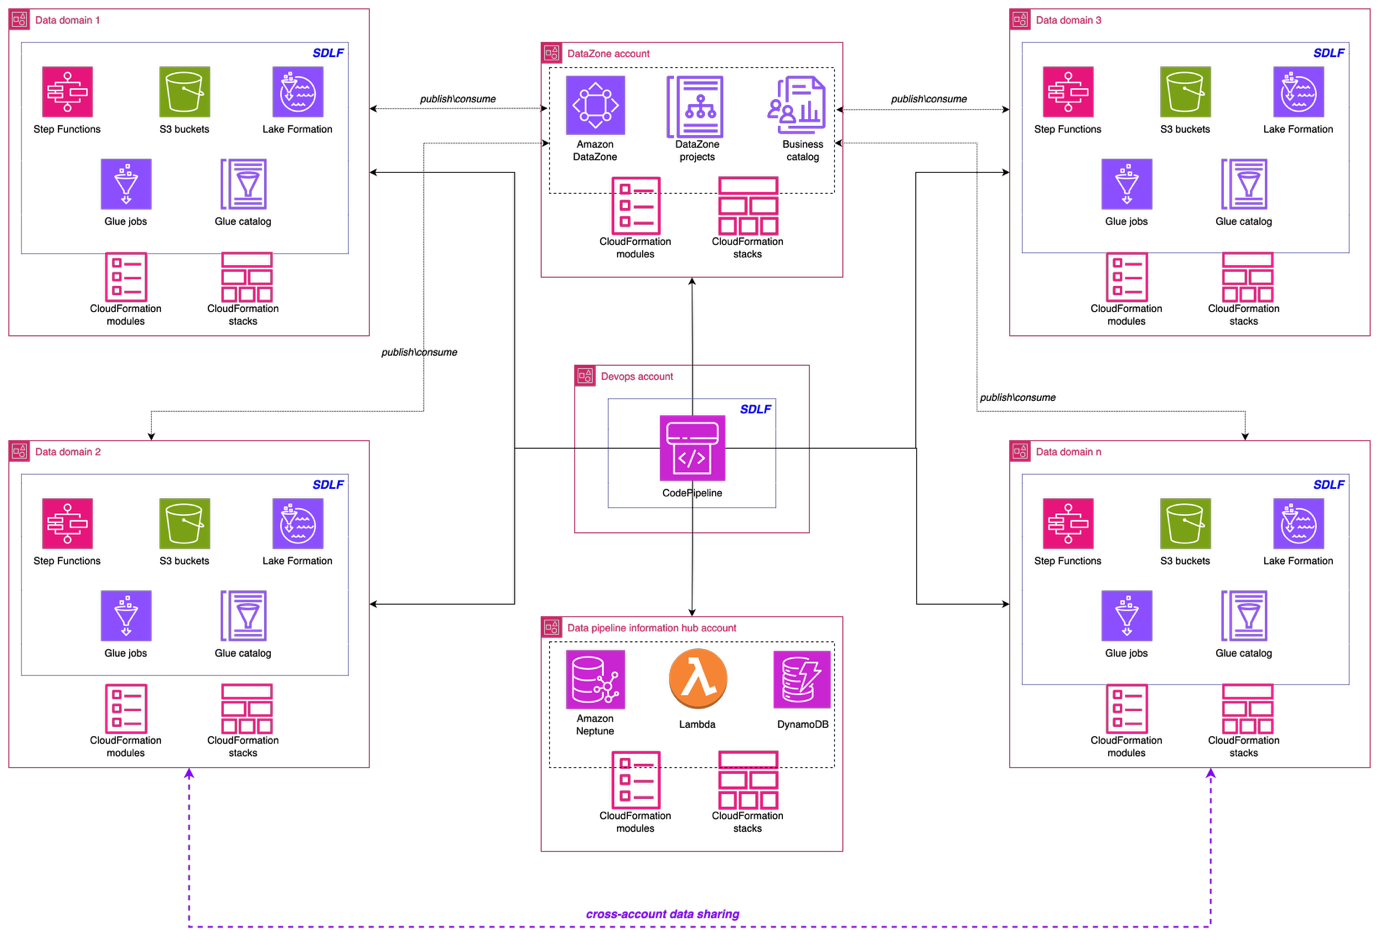
Previously, Data Catalog views required a definer role within the same AWS account as the base tables. The introduction of cross-account definer roles enables Data Catalog view creation in enterprise data mesh architectures. In this setup, database and table metadata is centralized in a governance account, and individual data owner accounts maintain control over table creation and management through their IAM roles. Data owner accounts can now create and manage Data Catalog views in the central governance accounts using their existing continuous integration and continuous delivery (CI/CD) pipeline roles.

In this post, we show you a cross-account scenario involving two AWS accounts: a central governance account containing the tables and hosting the views and a data owner (producer) account with the IAM role used to create and manage views. We provide implementation details for both SPARK dialect using AWS SDK code samples and ATHENA dialect using SQL commands. Using this approach, you can implement sophisticated data governance models at enterprise scale while maintaining operational efficiency across your AWS environment.

Key benefits

Key benefits for cross-account definer roles are as follows:

  • Enhanced data mesh support – Enterprises with multi-account data lakehouse architectures can now maintain their existing operational model where data owner accounts manage table creation and updates using their established IAM roles. These same roles can now create and manage Data Catalog views across account boundaries.
  • Strengthened security controls – By keeping table and view management within data owner account roles:
    • Security posture is enhanced through proper separation of duties.
    • Audit trails become more comprehensive and meaningful.
    • Access controls follow the principle of least privilege.
  • Elimination of data duplication – Data owner accounts can create views in central accounts that:
    • Provide access to specific data subsets without duplicating tables.
    • Reduce storage costs and management overhead.
    • Maintain a single source of truth while enabling targeted data sharing.

Solution overview

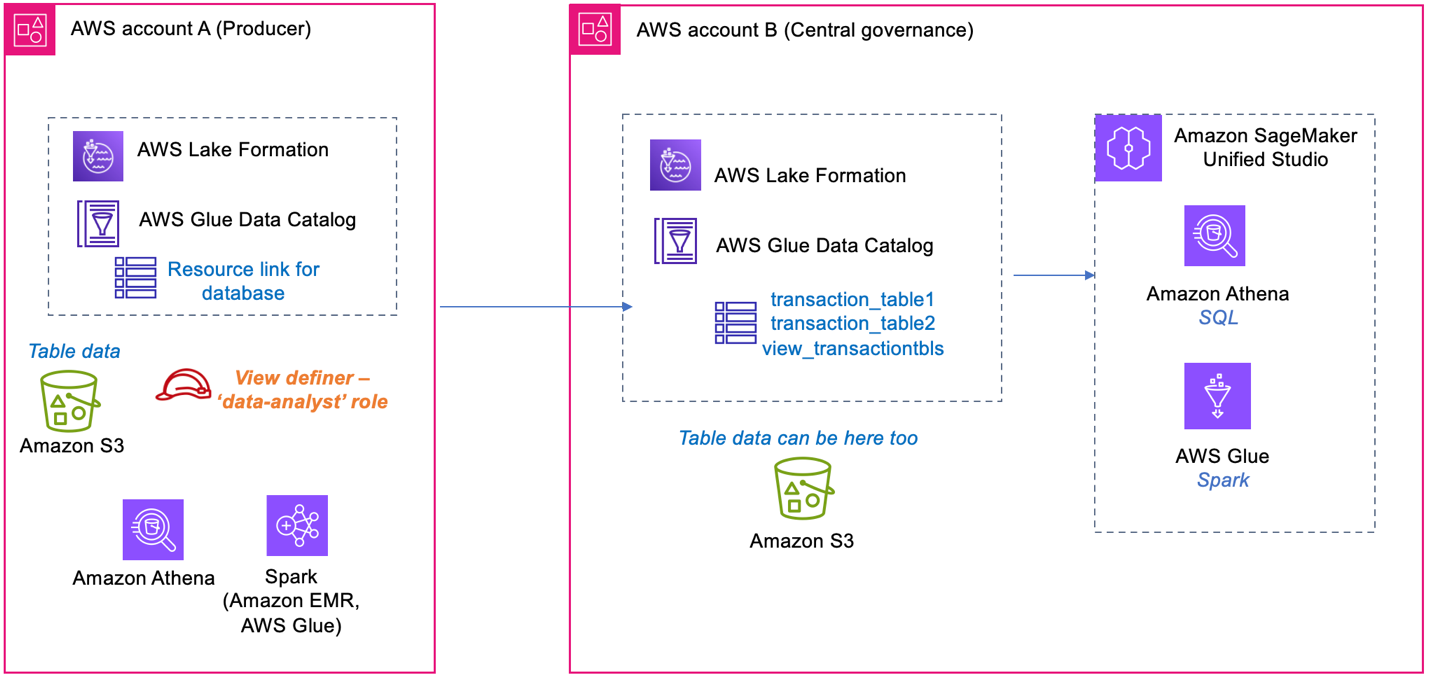
An example customer has a database with two transaction tables in their central account, where the catalog and permissions are maintained. With the database shared to the data owner (producer) account, we create a Data Catalog view in the central account on these two tables, using the producer’s definer role. The view from the central account can be shared to additional consumer accounts and queried. We illustrate creating the SPARK dialect using create-table CLI, and add the ATHENA dialect for the same view from the Athena console. We also provide the AWS SDK sample code for CreateTable() and UpdateTable(), with view definition and a sample pySpark script to read and verify the view in AWS Glue.

The following diagram shows the table, view, and definer IAM role placements between a central governance account and data producer account.

Prerequisites

To perform this solution, you need to have the following prerequisites:

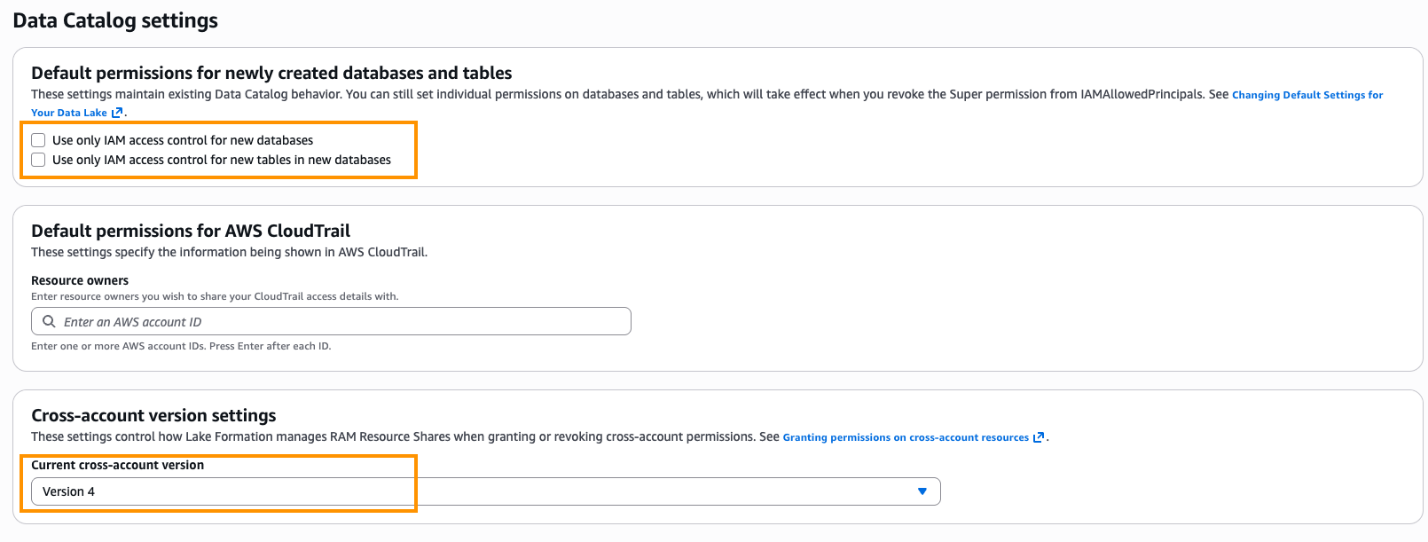
  1. Two AWS accounts with AWS Lake Formation set up. For details, refer to Set up AWS Lake Formation. The Lake Formation setup includes registering your IAM admin role as Lake Formation administrator. In the Data Catalog settings, shown in the following screenshot, Default permissions for newly created databases and tables is set to use Lake Formation permissions only. Cross-account version settings is set to Version 4.

  1. Create an IAM role Data-Analyst in the producer account. For the IAM permissions on this role, refer to Data analyst permissions. This role will also be used as the view definer role. Add the permissions to this definer role from the Prerequisites for creating views.

Create database and tables in the central account

In this step, you create two tables in the central governance account and populate them with few rows of data:

  1. Sign in to the central account as admin user. Open the Athena console and set up the Athena query results bucket.
  2. Run the following queries to create two sample Iceberg tables, representing bank customer transactions data:
/* Check if the Database exists, if not create new database. */
CREATE DATABASE IF NOT EXISTS bankdata_icebergdb;

/*Create transaction_table1*/ Replace the bucket name
CREATE TABLE bankdata_icebergdb.transaction_table1 (
  transaction_id string,
  transaction_type string,
  transaction_amount double)
LOCATION 's3://<bucket-name>/bankdata_icebergdb/transaction-table1'
TBLPROPERTIES (
  'table_type'='iceberg',
  'write_compression'='zstd'
);

/*Create transaction_table2*/
CREATE TABLE bankdata_icebergdb.transaction_table2 (
  transaction_id string,
  transaction_location string,
  transaction_date date)
LOCATION 's3://<bucket-name>/bankdata_icebergdb/transaction-table2'
TBLPROPERTIES (
  'table_type'='iceberg',
  'write_compression'='zstd'
);


INSERT INTO bankdata_icebergdb.transaction_table1 (transaction_id, transaction_type, transaction_amount)
VALUES
  ('T001', 'purchase', 50.0),
  ('T002', 'purchase', 120.0),
  ('T003', 'refund', 200.5),
  ('T004', 'purchase', 80.0),
  ('T005', 'withdrawal', 500.0),
  ('T006', 'purchase', 300.0),
  ('T007', 'deposit', 1000.0),
  ('T008', 'refund', 20.0),
  ('T009', 'purchase', 150.0),
  ('T010', 'withdrawal', 75.0);


INSERT INTO bankdata_icebergdb.transaction_table2 (transaction_id, transaction_location, transaction_date)
VALUES
  ('T001', 'Charlotte', DATE '2024-10-01'),
  ('T002', 'Seattle', DATE '2024-10-02'),
  ('T003', 'Chicago', DATE '2024-10-03'),
  ('T004', 'Miami', DATE '2024-10-04'),
  ('T005', 'New York', DATE '2024-10-05'),
  ('T006', 'Austin', DATE '2024-10-06'),
  ('T007', 'Denver', DATE '2024-10-07'),
  ('T008', 'Boston', DATE '2024-10-08'),
  ('T009', 'San Jose', DATE '2024-10-09'),
  ('T010', 'Phoenix', DATE '2024-10-10');
  1. Verify the created tables in Athena query editor by running a preview.

Share the database and tables from central to producer account

In the central governance account, you share the database and the two tables to the producer account and the Data-Analyst role in producer.

  1. Sign in to the Lake Formation console as the Lake Formation admin role.
  2. In the navigation pane, choose Data permissions.
  3. Choose Grant and provide the following information:
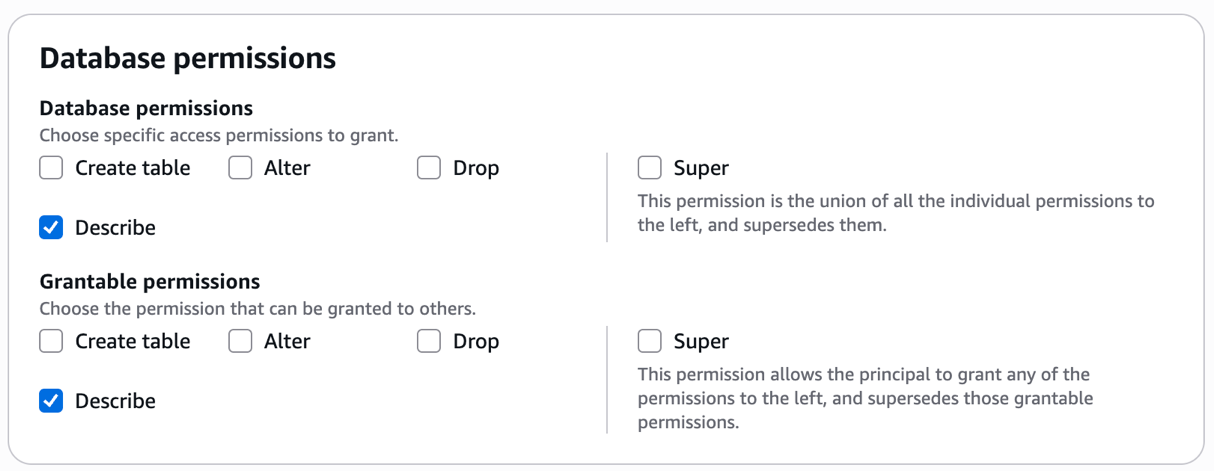
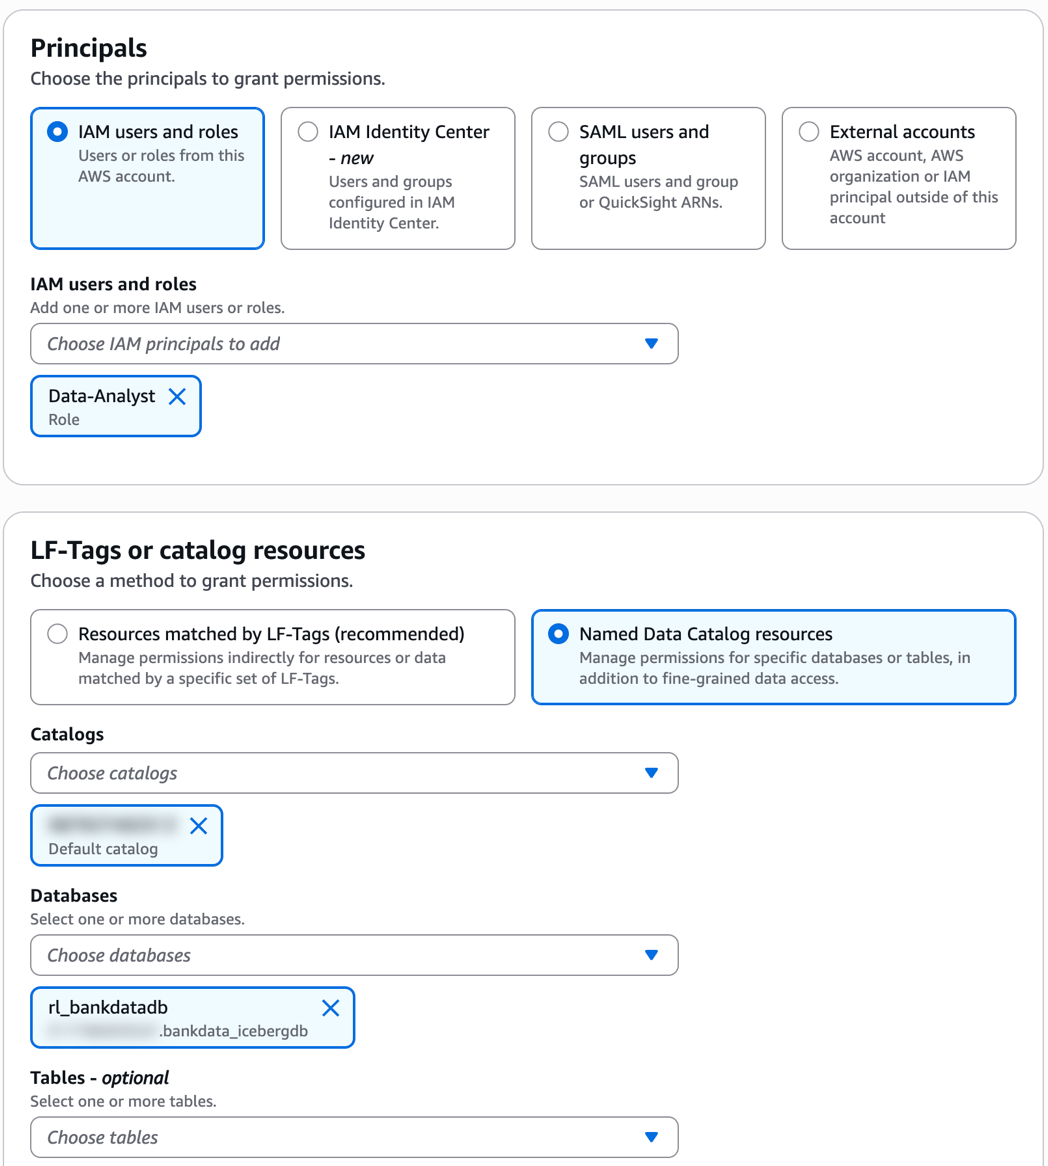
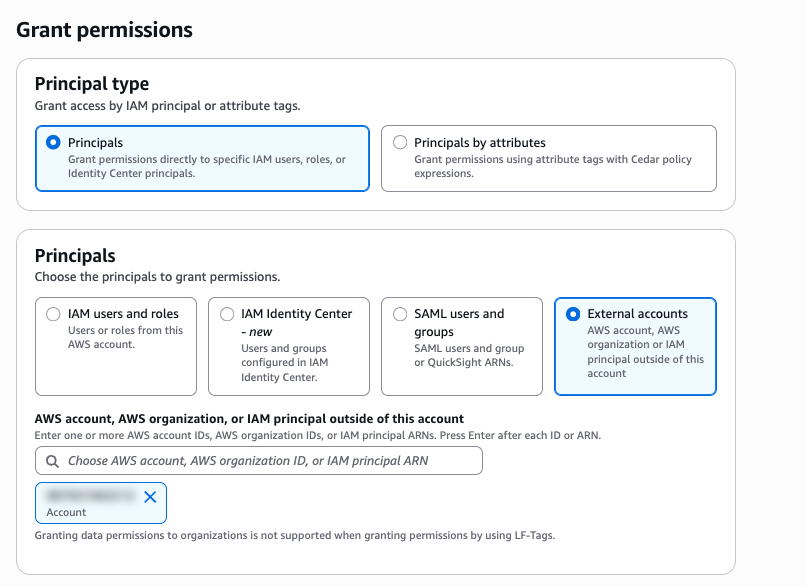
    1. For Principals, select External accounts and enter the producer account ID, as shown in the following screenshot.
    2. For Named Data Catalog Resources, select the default catalog and database bankdata_icebergdb, as shown in the following screenshot.
    3. Under Database permissions, select Describe. For Grantable permissions, select Describe.
    4. Choose Grant.
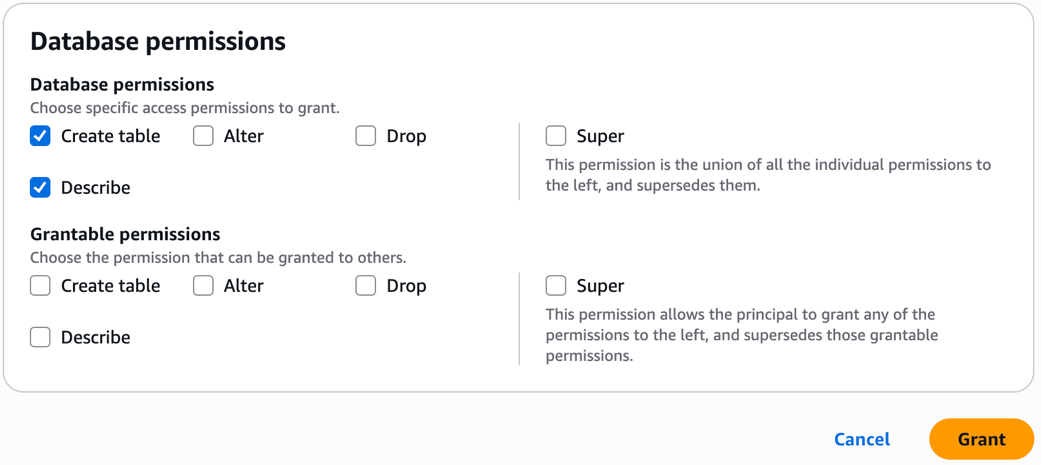
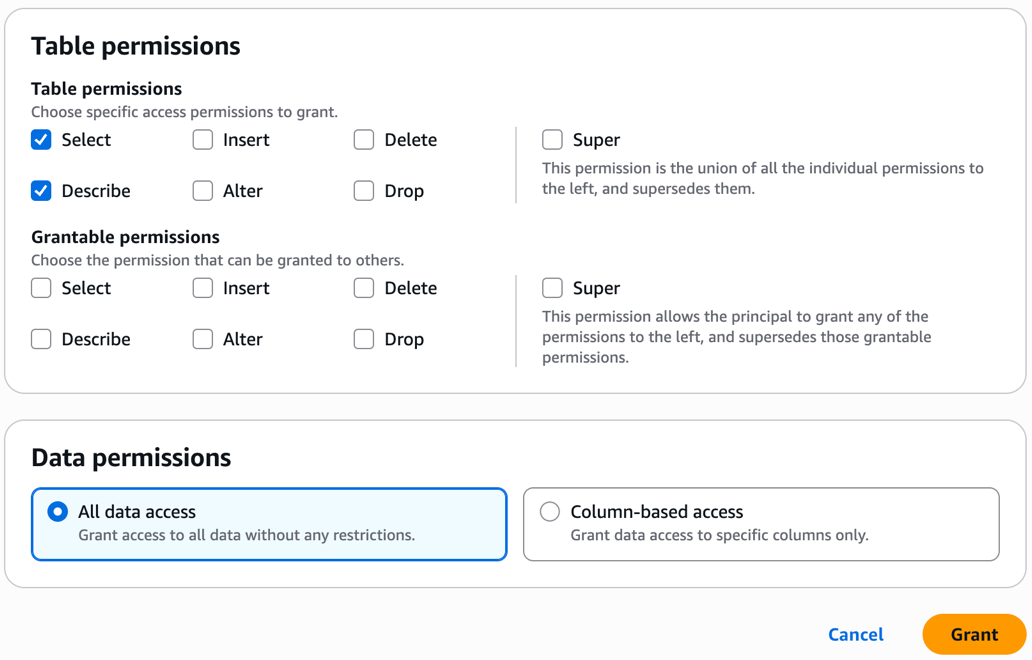
    5. Repeat the preceding steps to grant access to the producer account definer role Data-Analyst on the database bankdata_icebergdb and the two tables transaction_table1 and transaction_table2 as follows.
    6. Under Database permissions, grant Create table and Describe permissions.
    7. Under Table permissions, grant Select and Describe on all columns.

With these steps, the central governance account data admin steward has shared the database and tables to the producer account definer role.

Steps for producer account

Follow these steps for the producer account:

  1. Sign in to the Lake Formation console on the producer account as the Lake Formation administrator.
  2. In the left navigation pane, choose Databases. A blue banner will appear on the console, showing pending invitations from AWS Resource Access Manager (AWS RAM).
  3. Open the AWS RAM console and review the AWS RAM shares under Shared with me. You will see the AWS RAM shares in pending state. Select the pending AWS RAM share from central account and choose Accept resource share. After the resource share request is accepted, the shared database shows up in the producer account.
  4. On the Lake Formation console, select the database. On the Create dropdown list, choose Resource link. Provide a name rl_bank_iceberg and choose Create.
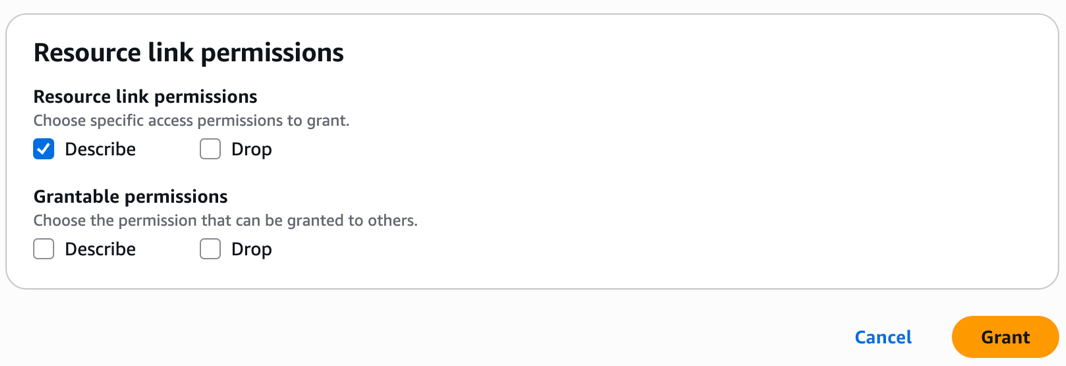
  5. Let’s grant Describe permission on the resource link to the Data-Analyst role in the producer account in the following steps.
    1. In the left navigation pane, choose Data permissions. Choose the Data-Analyst role. Select the resource link rl_bank_iceberg for the database as shown in the following screenshot.
    2. Grant Describe permission on the resource link.

Note: Cross-account Data Catalog views can’t be created using a resource link, although a resource link is needed for the SDK use of SPARK dialect.

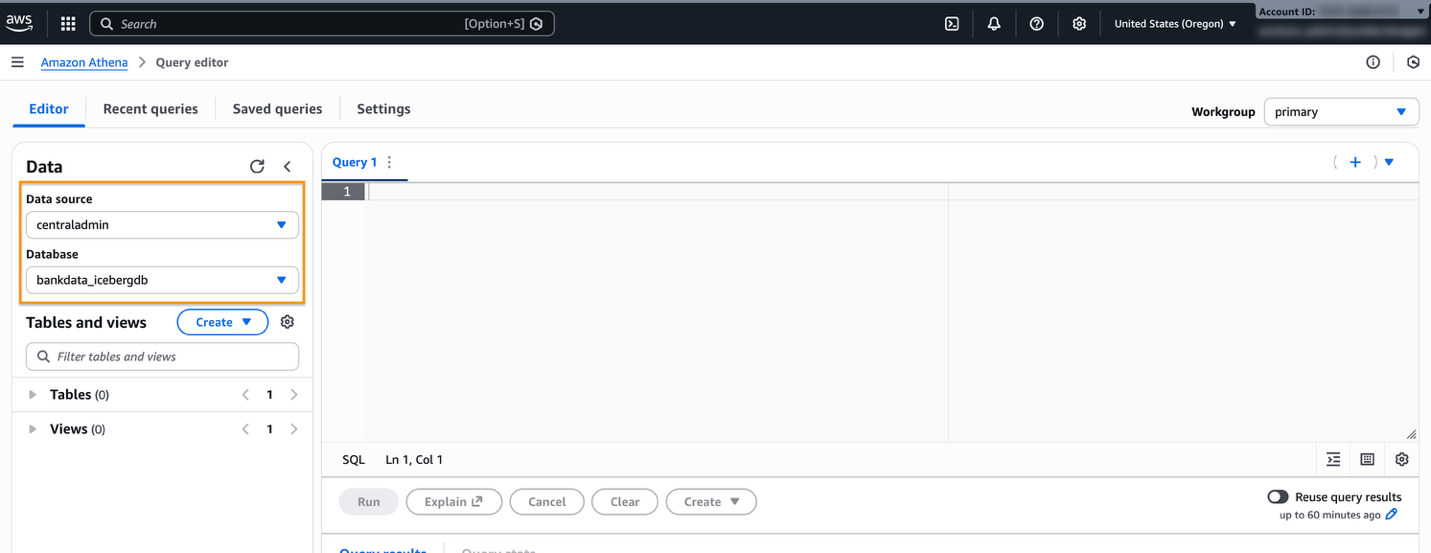
Next, add the central account Data Catalog as a Data Source in Athena from producer account:

  1. Open the Athena console.
  2. On the left navigation pane, choose Data sources and catalogs. Choose Create data source.
    1. Select S3-AWS Glue Data Catalog.
    2. Choose AWS – Glue Data Catalog in another account and name the data source as centraladmin.
    3. Choose Next and then create data source.

After the data source is created, navigate to the Query editor and verify the Data source centraladmin appears, as shown in the following screenshot.

The definer role can also now access and query the central catalog database.

Create SPARK dialect view

In this step, you create a view with SPARK dialect, using AWS Glue CLI command create-table:

  1. Sign in to the AWS console in the producer account as Data-Analyst role. Enter the following command in your CLI environment, such as AWS CloudShell, to create a SPARK DIALECT:
aws glue create-table --cli-input-json '{
   "DatabaseName": "rl_bank_iceberg",
   "TableInput": {
     "Name": "mdv_transaction1",
     "StorageDescriptor": {
       "Columns": [
         {
           "Name": "transaction_id",
           "Type": "string"
         },
         {
           "Name": "transaction_type",
           "Type": "string"
         },
         {
           "Name": "transaction_amount",
           "Type": "float"
         },
         {
           "Name": "transaction_location",
           "Type": "string"
         },
         {
           "Name": "transaction_date",
           "Type": "date"
         }
       ],
       "SerdeInfo": {}
     },
     "ViewDefinition": {
       "SubObjects": [
         "arn:aws:glue:<your-region>:<your-central-account-id>:table/bankdata_icebergdb/transaction_table1",
         "arn:aws:glue:<your-region>:<your-central-account-id>:table/bankdata_icebergdb/transaction_table2"
        ],
       "IsProtected": true,
       "Representations": [
         {
           "Dialect": "SPARK",
           "DialectVersion": "1.0",
           "ViewOriginalText": "SELECT t1.transaction_id, t1.transaction_type, t1.transaction_amount, t2.transaction_location, t2.transaction_date FROM transaction_table1 t1 JOIN transaction_table2 t2 ON t1.transaction_id = t2.transaction_id WHERE t1.transaction_amount > 100;",
           "ViewExpandedText": "SELECT t1.transaction_id, t1.transaction_type, t1.transaction_amount, t2.transaction_location, t2.transaction_date FROM transaction_table1 t1 JOIN transaction_table2 t2 ON t1.transaction_id = t2.transaction_id WHERE t1.transaction_amount > 100;"
         }
       ]
     }
   }
 }'
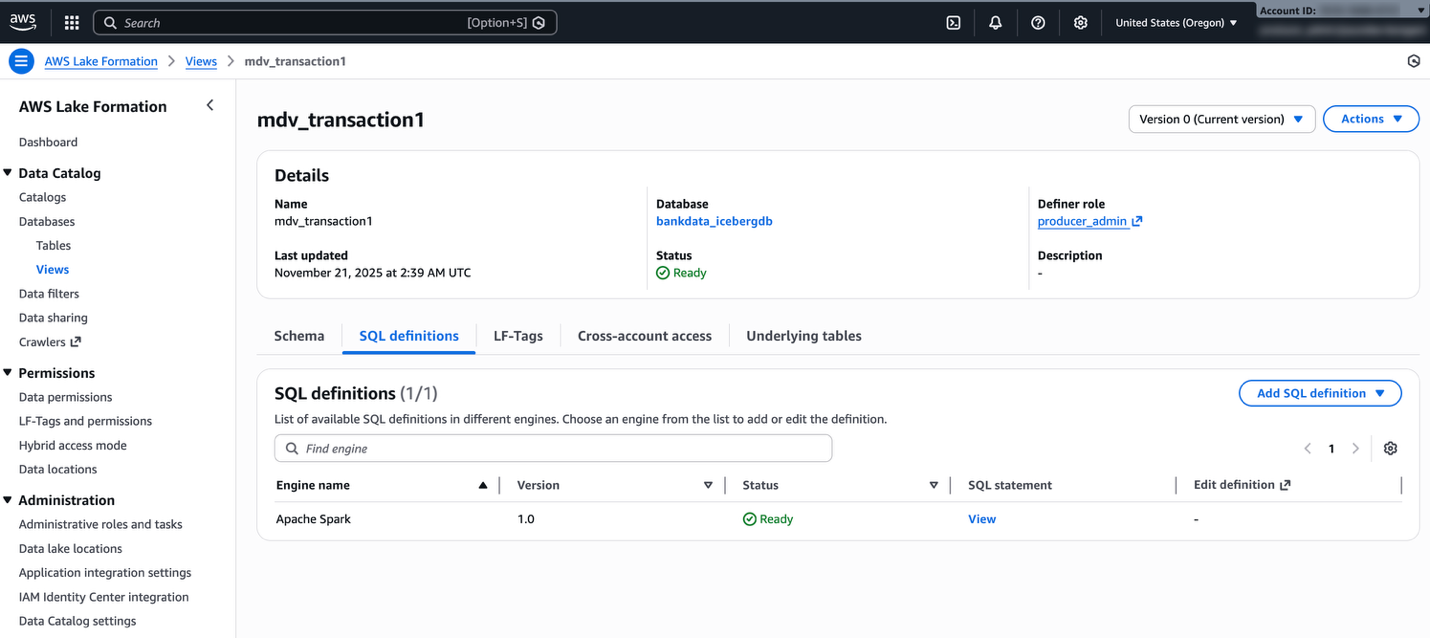
  1. Open the Lake Formation console and verify if the view is created. Verify the dialect of the view on the SQL definitions tab for the view details.

Add ATHENA dialect

To add ATHENA dialect, follow these steps:

  1. On the Athena console, select centraladmin from the Data source.
  2. Enter the following SQL script to create the ATHENA dialect for the same view:
ALTER VIEW mdv_transaction1 FORCE ADD DIALECT
AS
SELECT t1.transaction_id, t1.transaction_type, t1.transaction_amount, t2.transaction_location, t2.transaction_date FROM transaction_table1 t1 JOIN transaction_table2 t2 ON t1.transaction_id = t2.transaction_id WHERE t1.transaction_amount > 100

We can’t use the resource link rl_bank_iceberg in the Athena query editor to create or alter a view in the central account.

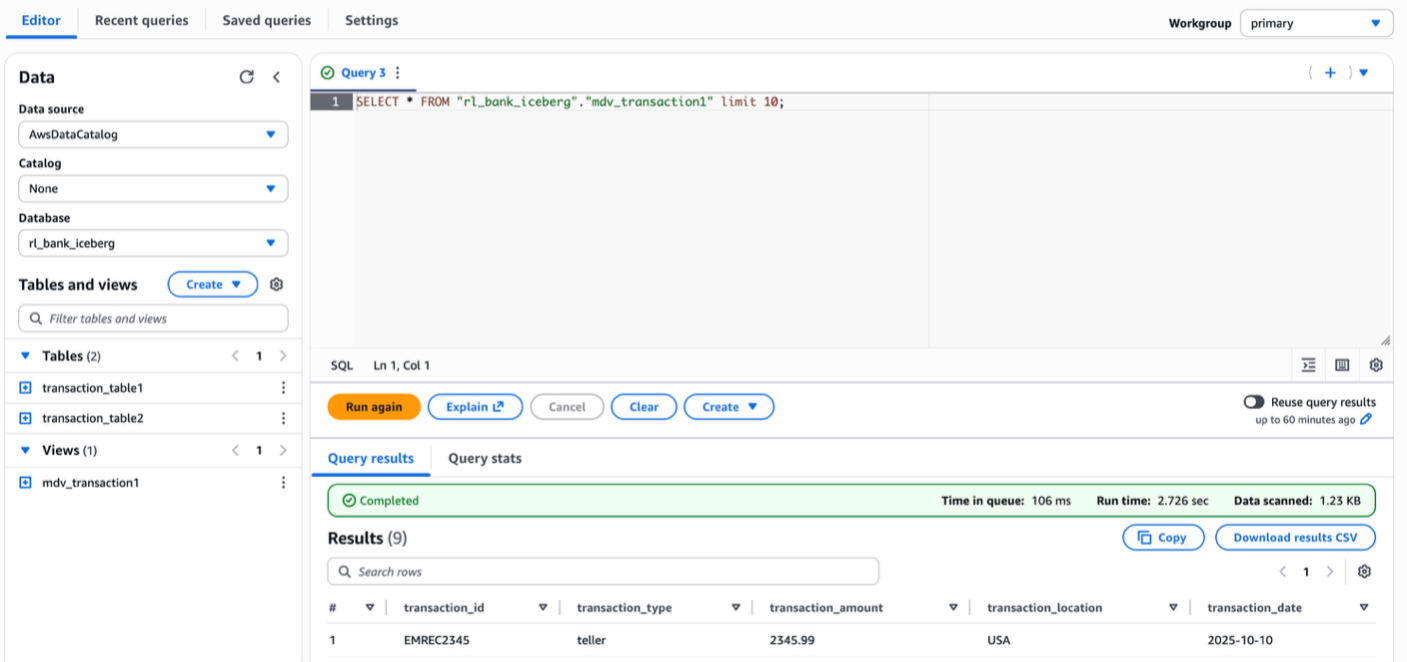
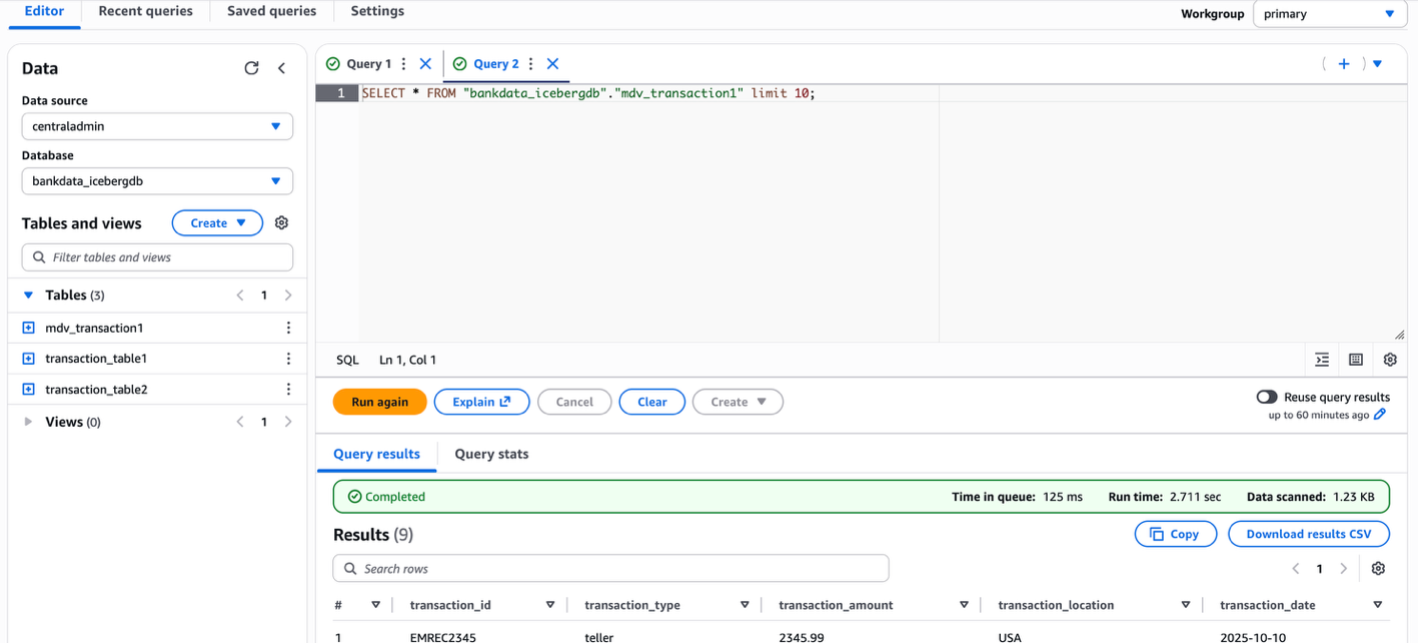
  1. Verify the added dialect by running a preview in Athena. For running the query, you can use either the resource link rl_bank_iceberg from the producer account catalog or use the centraladmin catalog.

The following screenshot shows querying using the resource link of the database in the producer account catalog.

The following screenshot shows querying the view from the producer using the connected catalog centraladmin as the data source.

  1. Verify the dialects on the view by inspecting the table in the Lake Formation console.

You can now query the view as the Data-Analyst role in the producer account, using both Athena and Spark. The view will also show in the central account as shown in the following code example, with access to the Lake Formation admin.

You can also create the view with ATHENA dialect and add the SPARK dialect. The SQL syntax to create the view in ATHENA dialect is shown in the following example:

create protected multi dialect view mdv_transaction1
security definer
as
SELECT t1.transaction_id, t1.transaction_type, t1.transaction_amount, t2.transaction_location, t2.transaction_date FROM transaction_table1 t1 
JOIN transaction_table2 t2 
ON t1.transaction_id = t2.transaction_id 
WHERE t1.transaction_amount > 100;

The update-table CLI to add the corresponding SPARK dialect is shown in the following example:

aws glue update-table --cli-input-json '{
    "DatabaseName": "rl_bankdatadb",
    "ViewUpdateAction": "ADD",
    "Force": true,
    "TableInput": {
        "Name": " mdv_transaction1",
        "StorageDescriptor": {
            "Columns": [
                {
                  "Name": "transaction_id",
                  "Type": "string"
                },
                {
                  "Name": "transaction_type",
                  "Type": "string"
                },
                {
                  "Name": "transaction_amount",
                  "Type": "float"
                },
                {
                  "Name": "transaction_location",
                  "Type": "string"
                },
                {
                  "Name": "transaction_date",
                  "Type": "date"
                }
             ],
             "SerdeInfo": {}
         },
         "ViewDefinition": {
         "SubObjects": [
               " "arn:aws:glue:<your-region>:<your-central-account-id>:table/bankdata_icebergdb/transaction_table1",
           "arn:aws:glue:<your-region>:<your-central-account-id>:table/bankdata_icebergdb/transaction_table2" 
],
         "IsProtected": true,
         "Representations": [
             {
                 "Dialect": "SPARK",
                 "DialectVersion": "1.0",
                 "ViewOriginalText": " SELECT t1.transaction_id, t1.transaction_type, t1.transaction_amount, t2.transaction_location, t2.transaction_date FROM transaction_table1 t1 JOIN transaction_table2 t2 ON t1.transaction_id = t2.transaction_id WHERE t1.transaction_amount > 100",
                 "ViewExpandedText": " SELECT t1.transaction_id, t1.transaction_type, t1.transaction_amount, t2.transaction_location, t2.transaction_date FROM transaction_table1 t1 JOIN transaction_table2 t2 ON t1.transaction_id = t2.transaction_id WHERE t1.transaction_amount > 100"
              }
           ]
        }
    }
}'

The following is a sample Python script to create a SPARK dialect view: glueview-createtable.py.

The following code block is a sample AWS Glue extract, transfer, and load (ETL) script to access the Spark dialect of the view from AWS Glue 5.0 from the central account. The AWS Glue job execution role should have Lake Formation SELECT permission on the AWS Glue view:

from pyspark.context import SparkContext
from pyspark.sql import SparkSession

aws_region = "<your-region>"
aws_account_id = "<your-central-account-id>"
local_catalogname = "spark_catalog"
warehouse_path = "s3://<your-bucket-name>/bankdata_icebergdb/transaction-table1"

spark = SparkSession.builder.appName('query_glue_view') \
    .config('spark.sql.extensions','org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions') \
    .config(f'spark.sql.catalog.{local_catalogname}', 'org.apache.iceberg.spark.SparkSessionCatalog') \
    .config(f'spark.sql.catalog.{local_catalogname}.catalog-impl', 'org.apache.iceberg.aws.glue.GlueCatalog') \
    .config(f'spark.sql.catalog.{local_catalogname}.client.region', aws_region) \
    .config(f'spark.sql.catalog.{local_catalogname}.glue.account-id', aws_account_id) \
    .config(f'spark.sql.catalog.{local_catalogname}.io-impl', 'org.apache.iceberg.aws.s3.S3FileIO') \
    .config(f'spark.sql.catalog.{local_catalogname}.warehouse',warehouse_path) \
    .getOrCreate()
spark.sql(f"show databases").show()
spark.sql(f"SHOW TABLES IN {local_catalogname}.bankdata_icebergdb").show()
spark.sql(f"SELECT * FROM {local_catalogname}.bankdata_icebergdb. mdv_transaction1").show()

In the AWS Glue job-details, for Lake Formation managed tables and for Iceberg tables, set additional parameters respectively as follows:

--enable-lakeformation-fine-grained-access = true
--datalake-formats = iceberg

Cleanup

To avoid incurring costs, clean up the resources you used for this post:

  1. Revoke the Lake Formation permissions granted to the Data-Analyst role and Producer account
  2. Drop the Athena tables
  3. Delete the Athena query results from your Amazon Simple Storage Service (Amazon S3) bucket
  4. Delete the Data-Analyst role from IAM

Conclusion

In this post, we demonstrated how to use cross-account IAM definer roles with AWS Glue Data Catalog views. We showed how data owner accounts can create and manage views in a central governance account while maintaining security and control over their data assets. This feature enables enterprises to implement sophisticated data mesh architectures without compromising on security or requiring data duplication.

The ability to use cross-account definer roles with Data Catalog views provides several key advantages:

  • Streamlines view management in multi-account environments
  • Maintains existing CI/CD workflows and automation
  • Enhances security through centralized governance
  • Reduces operational overhead by eliminating the need for data duplication

As organizations continue to build and scale their data lakehouse architectures across multiple AWS accounts, cross-account definer roles for Data Catalog views provide a crucial capability for implementing efficient, secure, and well-governed data sharing patterns.


About the authors

Aarthi Srinivasan

Aarthi Srinivasan

Aarthi is a Senior Big Data Architect at Amazon Web Services (AWS). She works with AWS customers and partners to architect data lake solutions, enhance product features, and establish best practices for data governance.

Sundeep Kumar

Sundeep Kumar

Sundeep is a Sr. Specialist Solutions Architect at Amazon Web Services (AWS), helping customers build data lake and analytics platforms and solutions. When not building and designing data lakes, Sundeep enjoys listening to music and playing guitar.

AWS analytics at re:Invent 2025: Unifying Data, AI, and governance at scale

Post Syndicated from Larry Weber original https://aws.amazon.com/blogs/big-data/aws-analytics-at-reinvent-2025-unifying-data-ai-and-governance-at-scale/

re:Invent 2025 showcased the bold Amazon Web Services (AWS) vision for the future of analytics, one where data warehouses, data lakes, and AI development converge into a seamless, open, intelligent platform, with Apache Iceberg compatibility at its core. Across over 18 major announcements spanning three weeks, AWS demonstrated how organizations can break down data silos, accelerate insights with AI, and maintain robust governance without sacrificing agility.

Amazon SageMaker: Your data platform, simplified

AWS introduced a faster, simpler approach to data platform onboarding for Amazon SageMaker Unified Studio. The new one-click onboarding experience eliminates weeks of setup, so teams can start working with existing datasets in minutes using their current AWS Identity and Access Management (IAM) roles and permissions. Accessible directly from Amazon SageMaker, Amazon Athena, Amazon Redshift, and Amazon S3 Tables consoles, this streamlined experience automatically creates SageMaker Unified Studio projects with existing data permissions intact. At its core is a powerful new serverless notebook that reimagines how data professionals work. This single interface combines SQL queries, Python code, Apache Spark processing, and natural language prompts, backed by Amazon Athena for Apache Spark to scale from interactive exploration to petabyte-scale jobs. Data engineers, analysts, and data scientists no longer need to context-switch between different tools based on workload—they can explore data with SQL, build models with Python, and use AI assistance, all in one place.

The introduction of Amazon SageMaker Data Agent in the new SageMaker notebooks marks a pivotal moment in AI-assisted development for data builders. This built-in agent doesn’t only generate code, it understands your data context, catalog information, and business metadata to create intelligent execution plans from natural language descriptions. When you describe an objective, the agent breaks down complex analytics and machine learning (ML) tasks into manageable steps, generates the required SQL and Python code, and maintains awareness of your notebook environment throughout the entire process. This capability transforms hours of manual coding into minutes of guided development, which means teams can focus on gleaning insights rather than repetitive boilerplate.

Embracing open data with Apache Iceberg

One significant theme across this year’s launches was the widespread adoption of Apache Iceberg across AWS analytics, transforming how organizations manage petabyte-scale data lakes. Catalog federation to remote Iceberg catalogs through the AWS Glue Data Catalog addresses a critical challenge in modern data architectures. You can now query remote Iceberg tables, stored in Amazon Simple Storage Service (Amazon S3) and catalogued in remote Iceberg catalogs, using preferred AWS analytics services such as Amazon Redshift, Amazon EMR, Amazon Athena, AWS Glue, and Amazon SageMaker, without moving or copying tables. Metadata synchronizes in real time, providing query results that reflect the current state. Catalog federation supports both coarse-grained access control and fine-grained access permissions through AWS Lake Formation enabling cross-account sharing and trusted identity propagation while maintaining consistent security across federated catalogs.

Amazon Redshift now writes directly to Apache Iceberg tables, enabling true open lakehouse architectures where analytics seamlessly span data warehouses and lakes. Apache Spark on Amazon EMR 7.12, AWS Glue, Amazon SageMaker notebooks, Amazon S3 Tables, and the AWS Glue Data Catalog now support Iceberg V3’s capabilities, including deletion vectors that mark deleted rows without expensive file rewrites, dramatically reducing pipeline costs and accelerating data modifications and row lineage. V3 automatically tracks every record’s history, creating audit trails essential for compliance and has table-level encryption that helps organizations meet stringent privacy regulations. These innovations mean faster writes, lower storage costs, comprehensive audit trails, and efficient incremental processing across your data architecture.

Governance that scales with your organization

Data governance received substantial attention at re:Invent with major enhancements to Amazon SageMaker Catalog. Organizations can now curate data at the column level with custom metadata forms and rich text descriptions, indexed in real time for immediate discoverability. New metadata enforcement rules require data producers to classify assets with approved business vocabulary before publication, providing consistency across the enterprise. The catalog uses Amazon Bedrock large language models (LLMs) to automatically suggest relevant business glossary terms by analyzing table metadata and schema information, bridging the gap between technical schemas and business language. Perhaps most importantly, SageMaker Catalog now exports its entire asset metadata as queryable Apache Iceberg tables through Amazon S3 Tables. This way, teams can analyze catalog inventory with standard SQL to answer questions like “which assets lack business descriptions?” or “how many confidential datasets were registered last month?” without building custom ETL infrastructure.

As organizations adopt multi-warehouse architectures to scale and isolate workloads, the new Amazon Redshift federated permissions capability eliminates governance complexity. Define data permissions one time from a Amazon Redshift warehouse, and they automatically enforce them across the warehouses in your account. Row-level, column-level, and masking controls apply consistently regardless of which warehouse queries originate from, and new warehouses automatically inherit permission policies. This horizontal scalability means organizations can add warehouses without increasing governance overhead, and analysts immediately see the databases from registered warehouses.

Accelerating AI innovation with Amazon OpenSearch Service

Amazon OpenSearch Service introduced powerful new capabilities to simplify and accelerate AI application development. With support for OpenSearch 3.3, agentic search enables precise results using natural language inputs without the need for complex queries, making it easier to build intelligent AI agents. The new Apache Calcite-powered PPL engine delivers query optimization and an extensive library of commands for more efficient data processing.

As seen in Matt Garman’s keynote, building large-scale vector databases is now dramatically faster with GPU acceleration and auto-optimization. Previously, creating large-scale vector indexes required days of building time and weeks of manual tuning by experts, which slowed innovation and prevented cost-performance optimizations. The new serverless auto-optimize jobs automatically evaluate index configurations—including k-nearest neighbors (k-NN) algorithms, quantization, and engine settings—based on your specified search latency and recall requirements. Combined with GPU acceleration, you can build optimized indexes up to ten times faster at 25% of the indexing cost, with serverless GPUs that activate dynamically and bill only when providing speed boosts. These advancements simplify scaling AI applications such as semantic search, recommendation engines, and agentic systems, so teams can innovate faster by dramatically reducing the time and effort needed to build large-scale, optimized vector databases.

Performance and cost optimization

Also announced in the keynote, Amazon EMR Serverless now eliminates local storage provisioning for Apache Spark workloads, introducing serverless storage that reduces data processing costs by up to 20% while preventing job failures from disk capacity constraints. The fully managed, auto scaling storage encrypts data in transit and at rest with job-level isolation, allowing Spark to release workers immediately when idle rather than keeping them active to preserve temporary data. Additionally, AWS Glue introduced materialized views based on Apache Iceberg, storing precomputed query results that automatically refresh as source data changes. Spark engines across Amazon Athena, Amazon EMR, and AWS Glue intelligently rewrite queries to use these views, accelerating performance by up to eight times while reducing compute costs. The service handles refresh schedules, change detection, incremental updates, and infrastructure management automatically.

The new Apache Spark upgrade agent for Amazon EMR transforms version upgrades from months-long projects into week-long initiatives. Using conversational interfaces, engineers express upgrade requirements in natural language while the agent automatically identifies API changes and behavioral modifications across PySpark and Scala applications. Engineers review and approve suggested changes before implementation, maintaining full control while the agent validates functional correctness through data quality checks. Currently supporting upgrades from Spark 2.4 to 3.5, this capability is available through SageMaker Unified Studio, Kiro CLI, or an integrated development environment (IDE) with Model Context Protocol compatibility.

For workflow optimization, AWS introduced a new Serverless deployment option for Amazon Managed Workflows for Apache Airflow (Amazon MWAA), which eliminates the operational overhead of managing Apache Airflow environments while optimizing costs through serverless scaling. This new offering addresses key challenges of operational scalability, cost optimization, and access management that data engineers and DevOps teams face when orchestrating workflows. With Amazon MWAA Serverless, data engineers can focus on defining their workflow logic rather than monitoring for provisioned capacity. They can now submit their Airflow workflows for execution on a schedule or on demand, paying only for the actual compute time used during each task’s execution.

Looking forward

These launches collectively represent more than incremental improvements. They signal a fundamental shift in how organizations are approaching analytics. By unifying data warehousing, data lakes, and ML under a common framework built on Apache Iceberg, simplifying access through intelligent interfaces powered by AI, and maintaining robust governance that scales effortlessly, AWS is giving organizations the tools to focus on insights rather than infrastructure. The emphasis on automation, from AI-assisted development to self-managing materialized views and serverless storage, reduces operational overhead while improving performance and cost efficiency. As data volumes continue to grow and AI becomes increasingly central to business operations, these capabilities position AWS customers to accelerate their data-driven initiatives with unprecedented simplicity and power. To view the Re:Invent 2025 Innovation Talk on analytics, visit Harnessing analytics for humans and AI on YouTube.


About the authors

Larry Weber

Larry Weber

Larry leads product marketing for the analytics portfolio at AWS.

Create and update Apache Iceberg tables with partitions in the AWS Glue Data Catalog using the AWS SDK and AWS CloudFormation

Post Syndicated from Aarthi Srinivasan original https://aws.amazon.com/blogs/big-data/create-and-update-apache-iceberg-tables-with-partitions-in-the-aws-glue-data-catalog-using-the-aws-sdk-and-aws-cloudformation/

In recent years, we’ve witnessed a significant shift in how enterprises manage and analyze their ever-growing data lakes. At the forefront of this transformation is Apache Iceberg, an open table format that’s rapidly gaining traction among large-scale data consumers.

However, as enterprises scale their data lake implementations, managing these Iceberg tables at scale becomes challenging. Data teams often need to manage table schema evolution, its partitioning, and snapshots versions. Automation streamlines these operations, provides consistency, reduces human error, and helps data teams focus on higher-value tasks.

The AWS Glue Data Catalog now supports Iceberg table management using the AWS Glue API, AWS SDKs, and AWS CloudFormation. Previously, users had to create Iceberg tables in the Data Catalog without partitions using CloudFormation or SDKs and later add partitions from Amazon Athena or other analytics engines. This prevents the table lineage from being tracked in one place and adds steps outside automation in the continuous integration and delivery (CI/CD) pipeline for table maintenance operations. With the launch, AWS Glue customers can now use their preferred automation or infrastructure as code (IaC) tools to automate Iceberg table creation with partitions and use the same tools to manage schema updates and sort order.

In this post, we show how to create and update Iceberg tables with partitions in the Data Catalog using the AWS SDK and CloudFormation.

Solution overview

In the following sections, we illustrate the AWS SDK for Python (Boto3) and AWS Command Line Interface (AWS CLI) usage of Data Catalog APIs—CreateTable() and UpdateTable()—for Amazon Simple Storage Service (Amazon S3) based Iceberg tables with partitions. We also provide the CloudFormation templates to create and update an Iceberg table with partitions.

Prerequisites

The Data Catalog API changes are made available in the following versions of the AWS CLI and SDK for Python:

  • AWS CLI version of 2.27.58 or above
  • SDK for Python version of 1.39.12 or above

AWS CLI usage

Let’s create an Iceberg table with one partition, using CreateTable() in the AWS CLI:

aws glue create-table --cli-input-json file://createicebergtable.json

The createicebergtable.json is as follows:

{
    "CatalogId": "123456789012",
    "DatabaseName": "bankdata_icebergdb",
    "Name": "transactiontable1",
    "OpenTableFormatInput": { 
      "IcebergInput": { 
         "MetadataOperation": "CREATE",
         "Version": "2",
         "CreateIcebergTableInput": { 
            "Location": "s3://sampledatabucket/bankdataiceberg/transactiontable1/",
            "Schema": {
                "SchemaId": 0,
                "Type": "struct",
                "Fields": [ 
                    { 
                        "Id": 1,
                        "Name": "transaction_id",
                        "Required": true,
                        "Type": "string"
                    },
                    { 
                        "Id": 2,
                        "Name": "transaction_date",
                        "Required": true,
                        "Type": "date"
                    },
                    { 
                        "Id": 3,
                        "Name": "monthly_balance",
                        "Required": true,
                        "Type": "float"
                    }
                ]
            },
            "PartitionSpec": { 
                "Fields": [ 
                    { 
                        "Name": "by_year",
                        "SourceId": 2,
                        "Transform": "year"
                    }
                ],
                "SpecId": 0
            },
            "WriteOrder": { 
                "Fields": [ 
                    { 
                        "Direction": "asc",
                        "NullOrder": "nulls-last",
                        "SourceId": 1,
                        "Transform": "none"
                    }
                ],
                "OrderId": 1
            }  
        }
      }
   }
}

The preceding AWS CLI command creates the metadata folder for the Iceberg table in Amazon S3, as shown in the following screenshot.

Amazon S3 bucket interface showing metadata folder containing single JSON file dated November 6, 2025

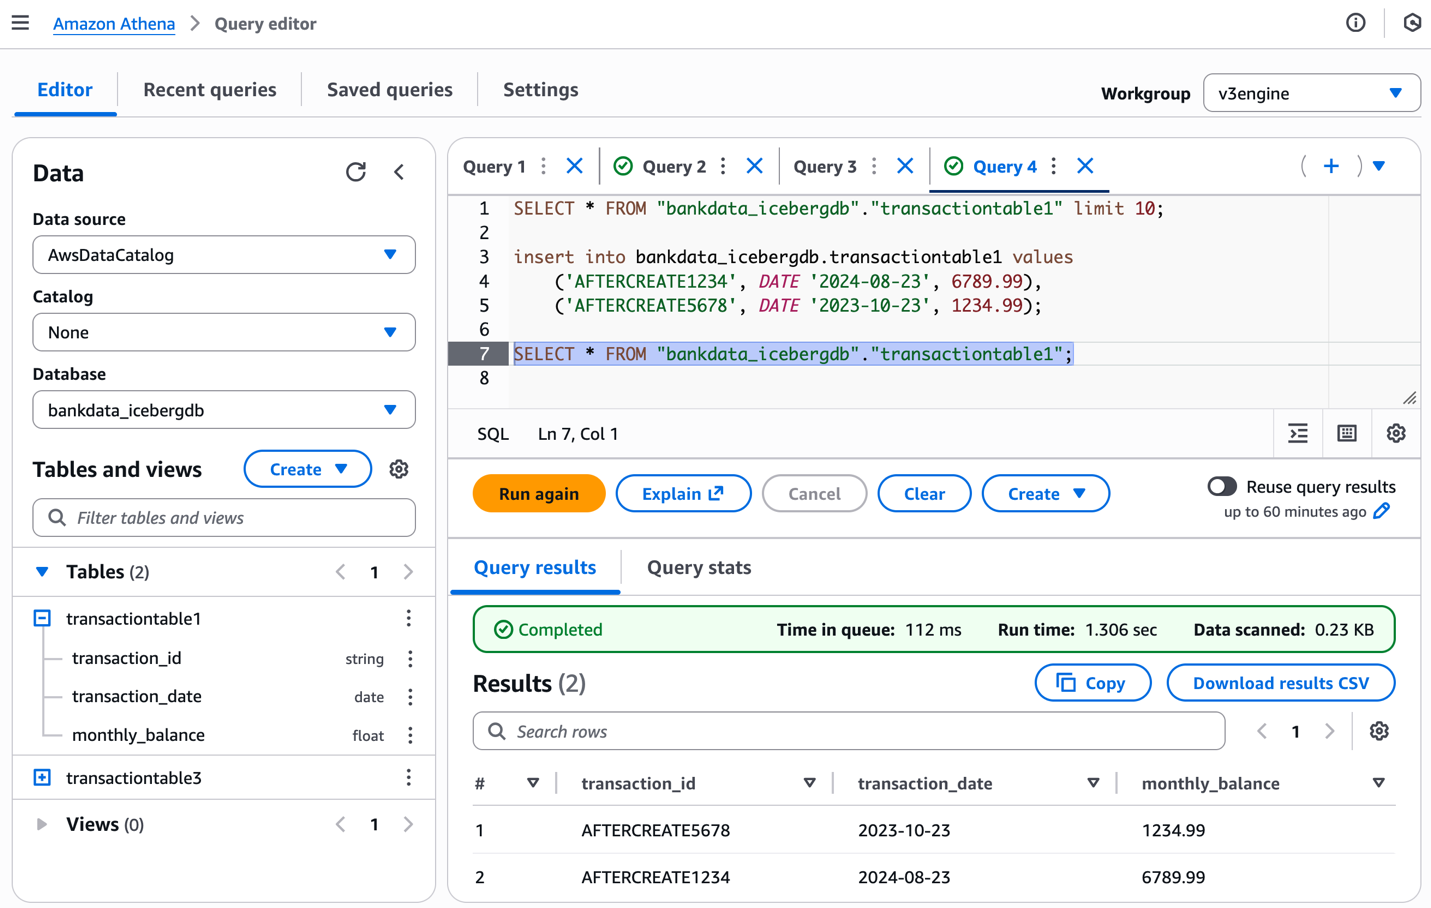
You can populate the table with values as follows and verify the table schema using the Athena console:

SELECT * FROM "bankdata_icebergdb"."transactiontable1" limit 10;
insert into bankdata_icebergdb.transactiontable1 values
    ('AFTERCREATE1234', DATE '2024-08-23', 6789.99),
    ('AFTERCREATE5678', DATE '2023-10-23', 1234.99);
SELECT * FROM "bankdata_icebergdb"."transactiontable1";

The following screenshot shows the results.

Amazon Athena query editor showing SQL queries and results for bankdata_icebergdb database with transaction data

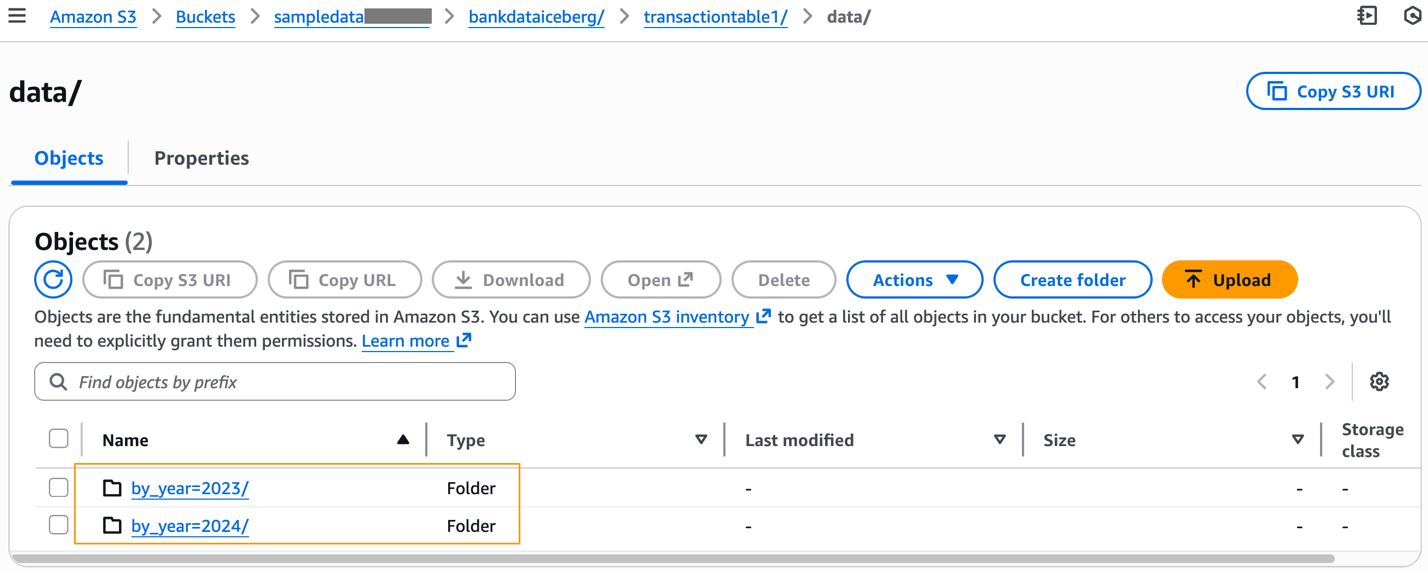
After populating the table with data, you can inspect the S3 prefix of the table, which will now have the data folder.

Amazon S3 bucket interface displaying data folder with two subfolders organized by year: 2023 and 2024

The data folders partitioned according to our table definition and Parquet data files created from our INSERT command are available under each partitioned prefix.

Amazon S3 bucket interface showing by_year=2023 folder containing single Parquet file of 575 bytes

Next, we update the Iceberg table by adding a new partition, using UpdateTable():

aws glue update-table --cli-input-json file://updateicebergtable.json

The updateicebergtable.json is as follows.

{
  "CatalogId": "123456789012",
  "DatabaseName": "bankdata_icebergdb",
  "Name": "transactiontable1",
  "UpdateOpenTableFormatInput": {
    "UpdateIcebergInput": {
      "UpdateIcebergTableInput": {
        "Updates": [
          {
            "Location": "s3://sampledatabucket/bankdataiceberg/transactiontable1/",
            "Schema": {
              "SchemaId": 1,
              "Type": "struct",
              "Fields": [
                {
                  "Id": 1,
                  "Name": "transaction_id",
                  "Required": true,
                  "Type": "string"
                },
                {
                  "Id": 2,
                  "Name": "transaction_date",
                  "Required": true,
                  "Type": "date"
                },
                {
                  "Id": 3,
                  "Name": "monthly_balance",
                  "Required": true,
                  "Type": "float"
                }
              ]
            },
            "PartitionSpec": {
              "Fields": [
                {
                  "Name": "by_year",
                  "SourceId": 2,
                  "Transform": "year"
                },
                {
                  "Name": "by_transactionid",
                  "SourceId": 1,
                  "Transform": "identity"
                }
              ],
              "SpecId": 1
            },
            "SortOrder": {
              "Fields": [
                {
                  "Direction": "asc",
                  "NullOrder": "nulls-last",
                  "SourceId": 1,
                  "Transform": "none"
                }
              ],
              "OrderId": 2
            }
          }
        ]
      }
    }
  }
}

UpdateTable() modifies the table schema by adding a metadata JSON file to the underlying metadata folder of the table in Amazon S3.

Amazon S3 bucket interface showing 5 metadata objects including JSON and Avro files with timestamps

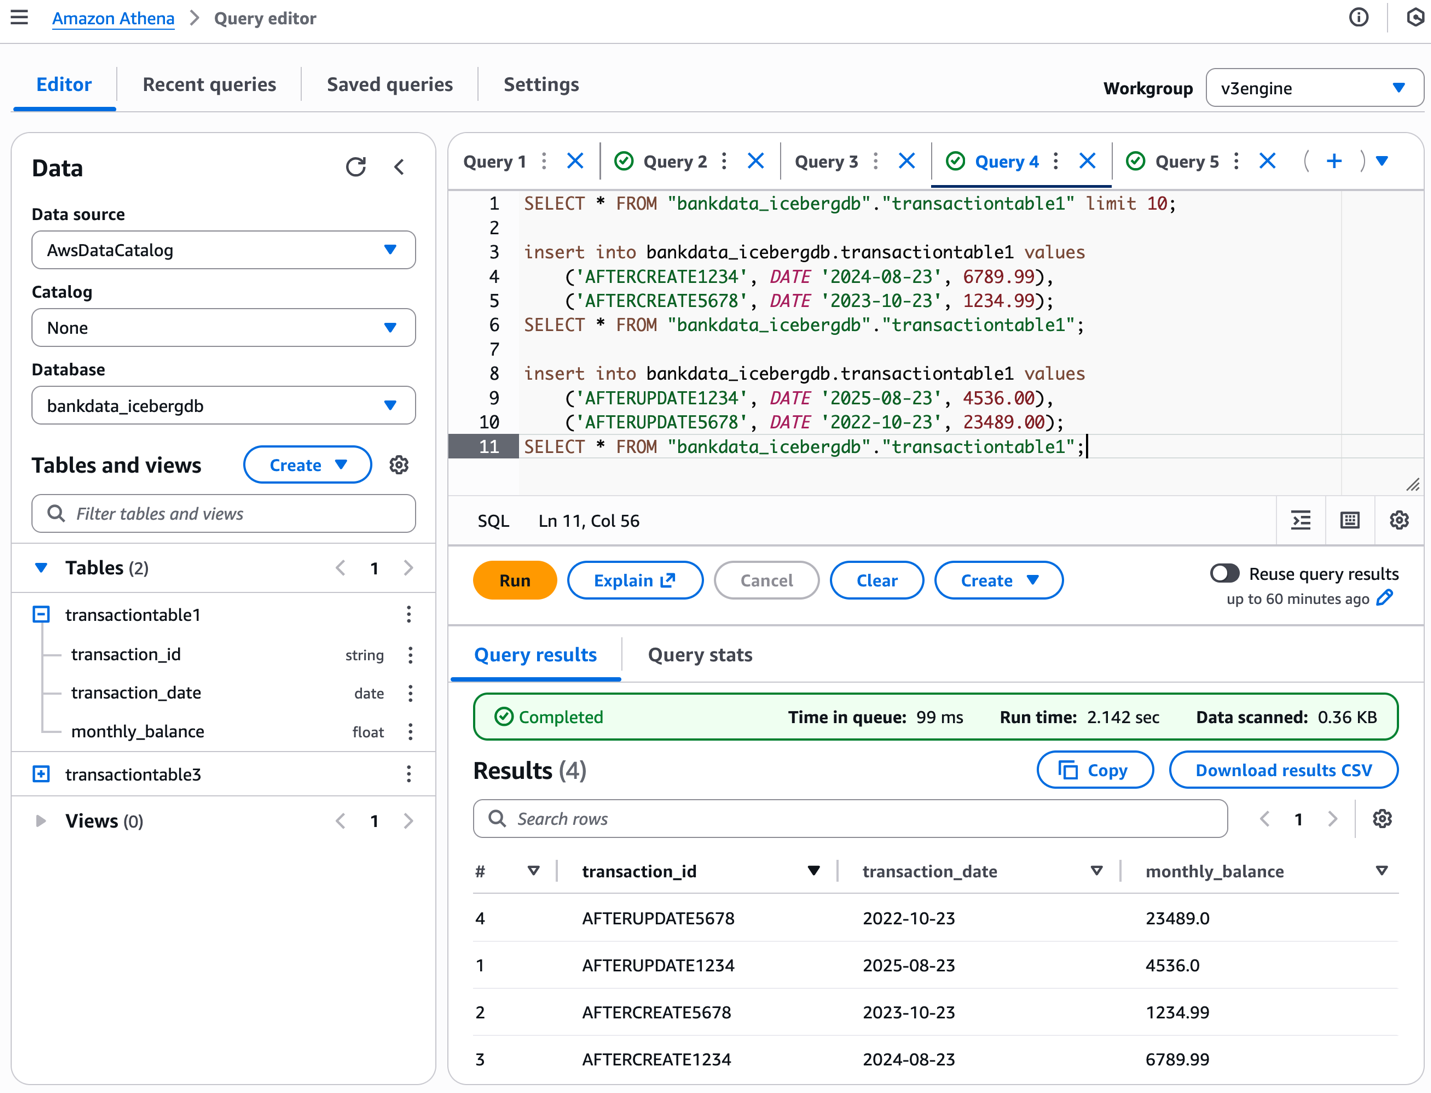
We insert values into the table using Athena as follows:

insert into bankdata_icebergdb.transactiontable1 values
    ('AFTERUPDATE1234', DATE '2025-08-23', 4536.00),
    ('AFTERUPDATE5678', DATE '2022-10-23', 23489.00);
SELECT * FROM "bankdata_icebergdb"."transactiontable1";

The following screenshot shows the results.

Amazon Athena query editor with SQL statements and results after iceberg partition update and insert data

Inspect the corresponding changes to the data folder in the Amazon S3 location of the table.

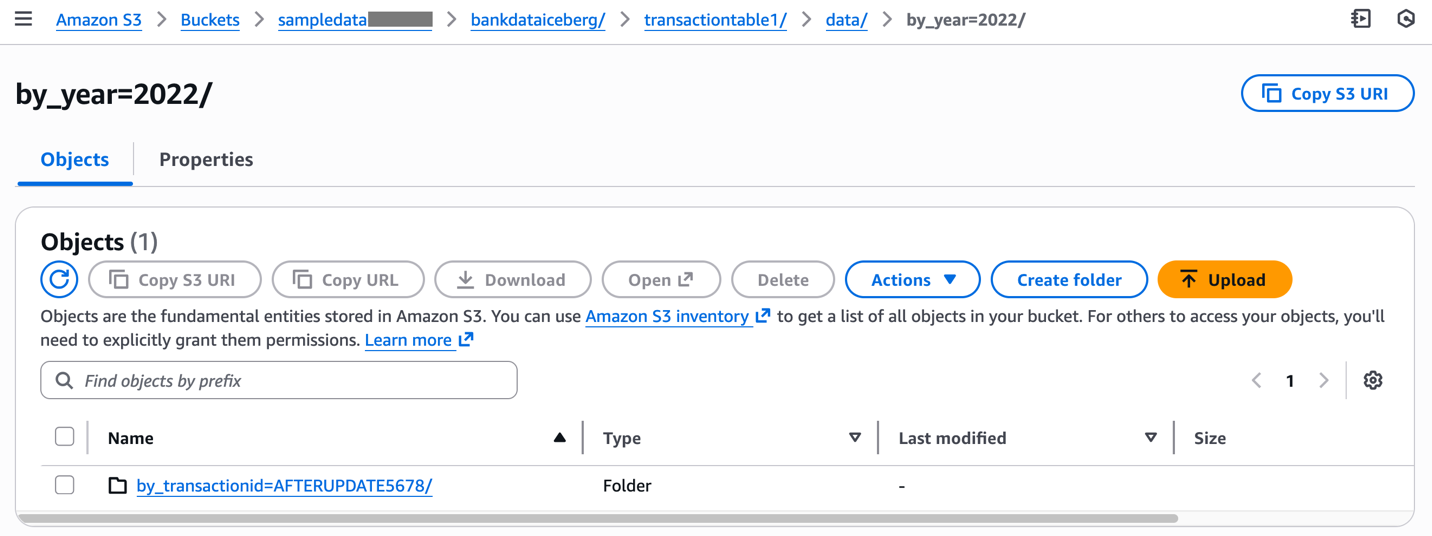
Amazon S3 prefix showing new partitions for the Iceberg table

This example has illustrated how to create and update Iceberg tables with partitions using AWS CLI commands.

SDK for Python usage

The following Python scripts illustrate using CreateTable() and UpdateTable() for an Iceberg table with partitions:

CloudFormation usage

Use the following CloudFormation templates for CreateTable() and UpdateTable(). After the CreateTable template is complete, update the same stack with the UpdateTable template by creating a new changeset for your stack and executing it.

Clean up

To avoid incurring costs on the Iceberg tables created using the AWS CLI, delete the tables from the Data Catalog.

Conclusion

In this post, we illustrated how to use the AWS CLI to create and update Iceberg tables with partitions in the Data Catalog. We also provided the SDK for Python and CloudFormation sample code and templates. We hope this helps you automate the creation and management of your Iceberg tables with partitions in your CI/CD pipelines and production environments. Try it out for your own use case and share your feedback in the comments section.


About the authors

Acknowledgements: A special thanks to everyone who contributed to the development and launch of this feature – Purvaja Narayanaswamy, Sachet Saurabh, Akhil Yendluri and Mohit Chandak.

Aarthi Srinivasan

Aarthi Srinivasan

Aarthi is a Senior Big Data Architect with AWS. She works with AWS customers and partners to architect data lake house solutions, enhance product features, and establish best practices for data governance.

Pratik Das

Pratik Das

Pratik is a Senior Product Manager with AWS. He is passionate about all things data and works with customers to understand their requirements and build delightful experiences. He has a background in building data-driven solutions and machine learning systems in production.

Introducing the Apache Spark troubleshooting agent for Amazon EMR and AWS Glue

Post Syndicated from Jake Zych original https://aws.amazon.com/blogs/big-data/introducing-the-apache-spark-troubleshooting-agent-for-amazon-emr-and-aws-glue/

The newly launched Apache Spark troubleshooting agent can eliminate hours of manual investigation for data engineers and scientists working with Amazon EMR or AWS Glue. Instead of navigating multiple consoles, sifting through extensive log files, and manually analyzing performance metrics, you can now diagnose Spark failures using simple natural language prompts. The agent automatically analyzes your workloads and delivers actionable recommendations. transforming a time-consuming troubleshooting process into a streamlined, efficient experience.

In this post, we show you how the Apache Spark troubleshooting agent helps analyze Apache Spark issues by providing detailed root causes and actionable recommendations. You’ll learn how to streamline your troubleshooting workflow by integrating this agent with your existing monitoring solutions across Amazon EMR and AWS Glue.

Apache Spark powers critical ETL pipelines, real-time analytics, and machine learning workloads across thousands of organizations. However, building and maintaining Spark applications remains an iterative process where developers spend significant time troubleshooting. Spark application developers encounter operational challenges due to a few different reasons:

  • Complex connectivity and configuration options to a variety of resources with Spark – Although this makes Spark a popular data processing platform, it often makes it challenging to find the root cause of inefficiencies or failures when Spark configurations aren’t optimally or correctly configured.
  • Spark’s in-memory processing model and distributed partitioning of datasets across its workers – Although good for parallelism, this often makes it difficult for users to identify inefficiencies. This results in slow application execution or root cause of failures caused by resource exhaustion issues such as out of memory and disk exceptions.
  • Lazy evaluation of Spark transformations – Although lazy evaluation optimizes performance, it makes it challenging to accurately and quickly identify the application code and logic that caused the failure from the distributed logs and metrics emitted from different executors.

Apache Spark troubleshooting agent architecture

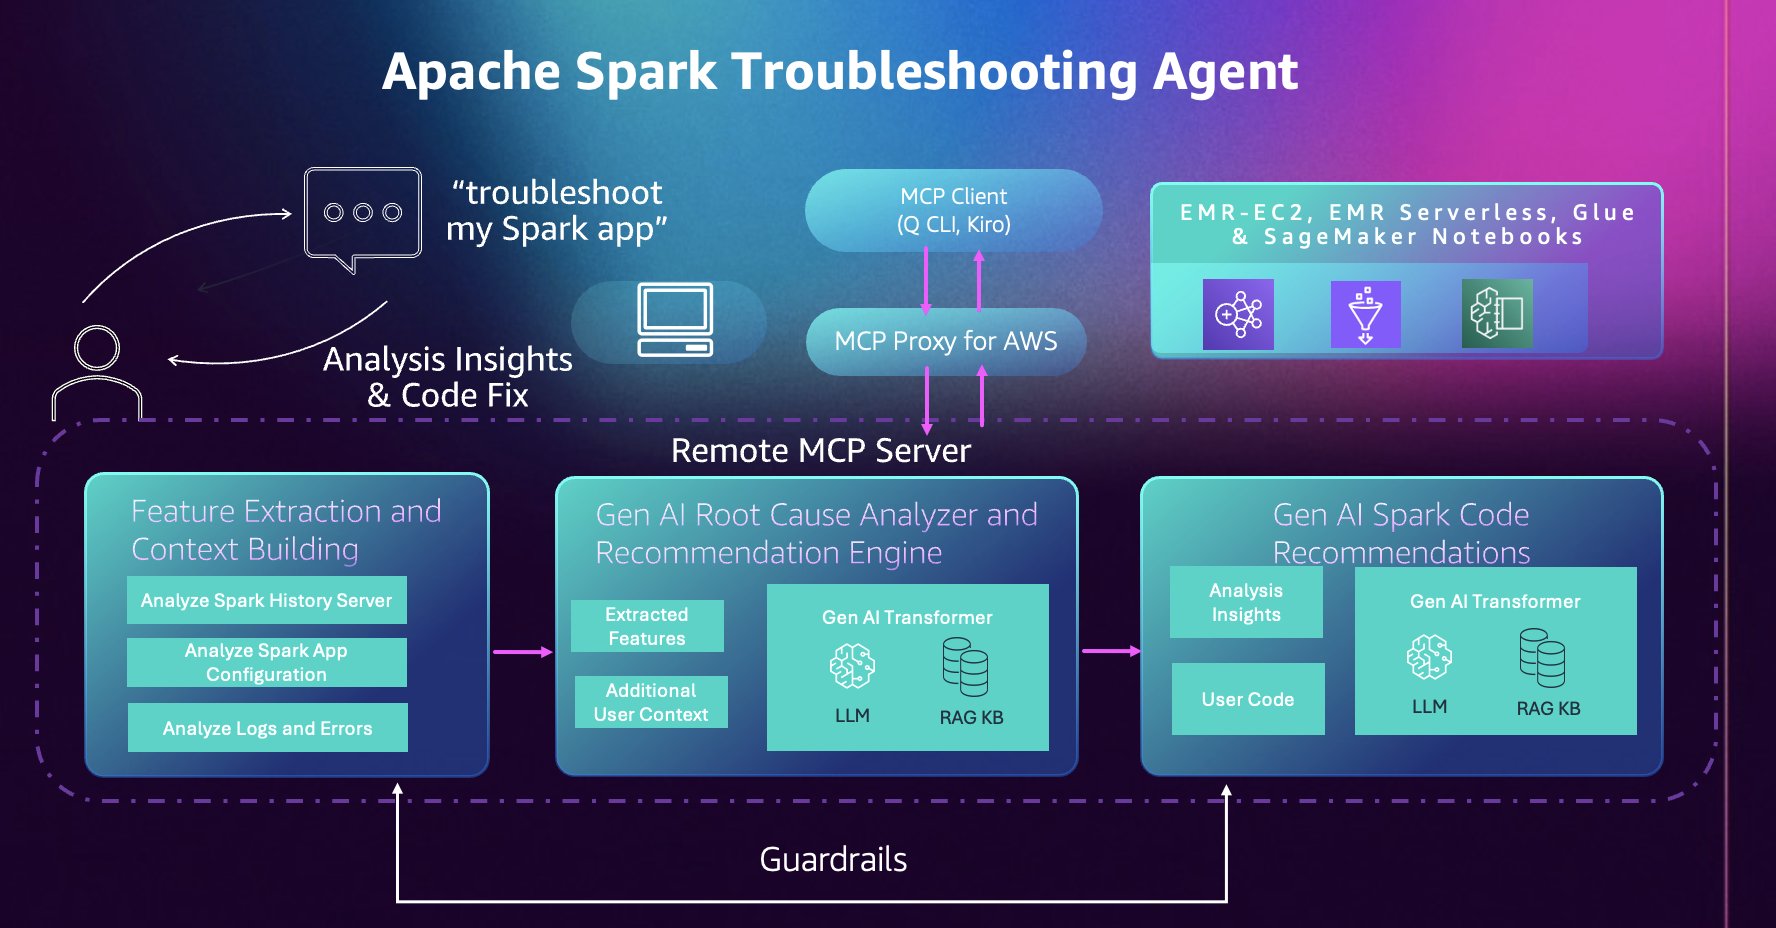
This section describes the components of the troubleshooting agent and how they connect to your development environment. The troubleshooting agent provides a single conversational entry point for your Spark applications across Amazon EMR, AWS Glue, and Amazon SageMaker Notebooks. Instead of navigating different consoles, APIs, and log locations for each service, you interact with one Model Context Protocol (MCP) server through natural language using any MCP-compatible AI assistant of your choice, including custom agents you develop using frameworks such as Strands Agents.

Operating as a fully managed cloud-hosted MCP server, the agent removes the need to maintain local servers while keeping your data and code isolated and secure in a single-tenant system design. Operations are read-only and backed by AWS Identity and Access Management (IAM) permissions; the agent only has access to resources and actions your IAM role grants. Additionally, tool calls are automatically logged to AWS CloudTrail, providing complete auditability and compliance visibility. This combination of managed infrastructure, granular IAM controls, and CloudTrail integration confirms your Spark diagnostic workflows remain secure, compliant, and fully auditable.

The agent builds on years of AWS expertise running millions of Spark applications at scale. It automatically analyzes Spark History Server data, distributed executor logs, configuration patterns, and error stack traces and extracts relevant features and signals to surface insights that would otherwise require manual correlation across multiple data sources and deep understanding of Spark and service internals.

Getting started 

Complete the following steps to get started with the Apache Spark troubleshooting agent.

Prerequisites

Verify you meet or have completed the following prerequisites.

System requirements:

  • Python 3.10 or higher
  • Install the uv package manager. For instructions, see installing uv.
  • AWS Command Line Interface (AWS CLI) (version 2.30.0 or later) installed and configured with appropriate credentials.

IAM permissions: Your AWS IAM profile needs permissions to invoke the MCP server and access your Spark workload resources. The AWS CloudFormation template in the setup documentation creates an IAM role with the required permissions. You can also manually add the required IAM permissions.

Set up using AWS CloudFormation

First, deploy the AWS CloudFormation template provided in the setup documentation. This template automatically creates the IAM roles with the permissions required to invoke the MCP server.

  1. Deploy the template within the same AWS Region you run your workloads in. For this post, we’ll use us-east-1.
  2. From the AWS CloudFormation Outputs tab, copy and execute the environment variable command:
    export SMUS_MCP_REGION=us-east-1 && export IAM_ROLE=arn:aws:iam::111122223333:role/spark-troubleshooting-role-xxxxxx

  3. Configure your AWS CLI profile:
    aws configure set profile.smus-mcp-profile.role_arn ${IAM_ROLE}
    aws configure set profile.smus-mcp-profile.source_profile default
    aws configure set profile.smus-mcp-profile.region ${SMUS_MCP_REGION}

Set up using Kiro CLI

You can use Kiro CLI to interact with the Apache Spark troubleshooting agent directly from your terminal.

Installation and configuration:

  1. Install Kiro CLI.
  2. Add both MCP servers, using the environment variables from the previous Set up using AWS CloudFormation section:
    # Add Spark Troubleshooting MCP Server
    kiro-cli-chat mcp add \
        --name "sagemaker-unified-studio-mcp-troubleshooting" \
        --command "uvx" \
        --args "[\"mcp-proxy-for-aws@latest\",\"https://sagemaker-unified-studio-mcp.${SMUS_MCP_REGION}.api.aws/spark-troubleshooting/mcp\", \"--service\", \"sagemaker-unified-studio-mcp\", \"--profile\", \"smus-mcp-profile\", \"--region\", \"${SMUS_MCP_REGION}\", \"--read-timeout\", \"180\"]" \
        --timeout 180000 \
        --scope global
    # Add Spark Code Recommendation MCP Server
    kiro-cli-chat mcp add \
        --name "sagemaker-unified-studio-mcp-code-rec" \
        --command "uvx" \
        --args "[\"mcp-proxy-for-aws@latest\",\"https://sagemaker-unified-studio-mcp.${SMUS_MCP_REGION}.api.aws/spark-code-recommendation/mcp\", \"--service\", \"sagemaker-unified-studio-mcp\", \"--profile\", \"smus-mcp-profile\", \"--region\", \"${SMUS_MCP_REGION}\", \"--read-timeout\", \"180\"]" \
        --timeout 180000 \
        --scope global

  3. Verify your setup by running the /tools command in Kiro CLI to see the available Apache Spark troubleshooting tools.

Set up using Kiro IDE

Kiro IDE provides a visual development environment with integrated AI assistance for interacting with the Apache Spark troubleshooting agent.

Installation and configuration:

  1. Install Kiro IDE.
  2. MCP configuration is shared across Kiro CLI and Kiro IDE. Open the command palette using Ctrl + Shift + P (Windows / Linux) or Cmd + Shift + P (macOS) and Search for Kiro: Open MCP Config
  3. Verify the contents of your mcp.json match the Set up using Kiro CLI section.

Using the troubleshooting agent

Next, we provide 3 reference architectures for solutions to use the troubleshooting agent in your existing workflows with ease. We also provide the reference code and AWS CloudFormation templates for these architectures in the Amazon EMR Utilities GitHub repository.

Solution 1 – Conversational troubleshooting: Troubleshooting failed Apache Spark applications with Kiro CLI

When Spark applications fail across your data platform, your debugging approach would typically involve navigating different consoles for Amazon EMR, Amazon EC2, Amazon EMR Serverless, and AWS Glue, manually reviewing Spark History Server logs, checking error stack traces, analyzing resource usage patterns, then correlating this information to find the root cause and fix. The Apache Spark troubleshooting agent automates this entire workflow through natural language, providing a unified troubleshooting experience across the three platforms. Simply describe your failed applications, for example:

# Amazon EMR-EC2
Debug my failing Amazon EMR-EC2 step. Cluster id: 'j-xxxxx' Step id: 's-xxxxx'
# Amazon EMR Serverless
Troubleshoot my Amazon EMR Serverless job. Application id: 'xxxxx' Job run id: 'xxxxx'
# AWS Glue
Analyze my failed AWS Glue job. Job name: 'my-etl-job' Job run id: 'jr_xxxxx'

The agent automatically extracts Spark event logs and metrics, analyzes the error patterns, and provides a clear root cause explanation along with recommendations, all through the same conversational interface. The following video demonstrates the complete troubleshooting workflow across Amazon EMR-EC2, Amazon EMR Serverless, and AWS Glue using Kiro CLI:

Solution 2 – Agent-driven notifications: Integrate the Apache Spark troubleshooting agent into a monitoring workflow 

In addition to troubleshooting from the command line, the troubleshooting agent can plug into your monitoring infrastructure to provide improved failure notifications.

Production data pipelines require immediate visibility when failures occur. Traditional monitoring systems can alert you when a Spark job fails, but diagnosing the root cause still requires manual investigation and an analysis of what went wrong before remediation can begin.

With the Apache Spark troubleshooting agent, you can integrate it into your existing monitoring workflows to receive root causes and recommendations as soon as you receive a failure notification. Here, we demonstrate two integration patterns that result in automatic root cause analysis within your existing workflows.

Apache Airflow Integration

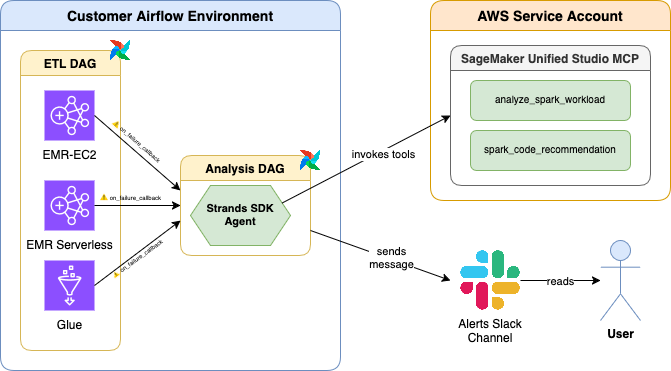
This first integration pattern uses Apache Airflow callbacks to automatically trigger troubleshooting when Spark job operators fail.

When any Amazon EMR, Amazon EC2, Amazon EMR Serverless, or AWS Glue job operator fails in an Apache Airflow DAG,

  1. A callback invokes the Spark troubleshooting agent within a separate DAG.
  2. The Spark troubleshooting agent analyzes the issue, establishes the root cause, and identifies code fix recommendations.
  3. The Spark troubleshooting agent sends a comprehensive diagnostic report to a configured Slack channel.

The solution is available in the Amazon EMR Utilities GitHub repository (documentation) for immediate integration into your existing Apache Airflow deployments with a 1-line change to your Airflow DAGs. The following video demonstrates this integration:

Amazon EventBridge integration

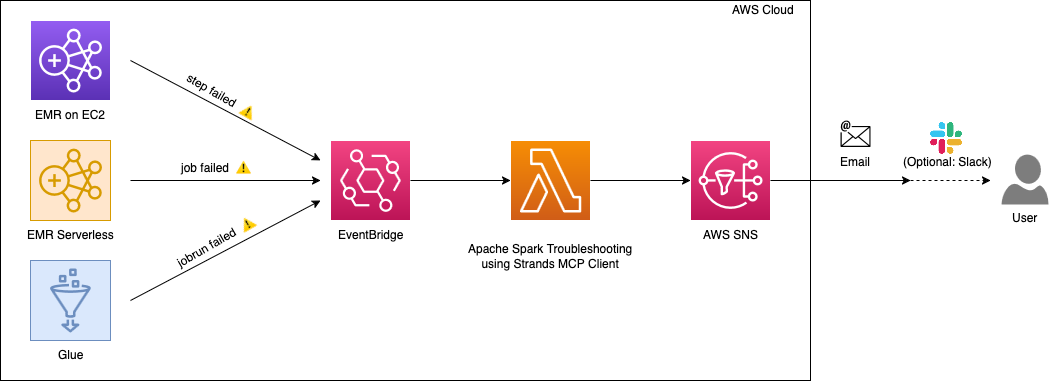
For event-driven architectures, this second pattern uses Amazon EventBridge to automatically invoke the troubleshooting agent when Spark jobs fail across your AWS environment.

This integration uses an AWS Lambda function that interacts with the Apache Spark troubleshooting agent through the Strands MCP Client.

When Amazon EventBridge detects failures from Amazon EMR-EC2 steps, Amazon EMR Serverless job runs, or AWS Glue job runs, it triggers the AWS Lambda function which:

  1. Uses the Apache Spark troubleshooting agent to analyze the failure
  2. Identifies the root cause and generates code fix recommendations
  3. Constructs a comprehensive analysis summary
  4. Sends the summary to Amazon SNS
  5. Delivers the analysis to your configured destinations (email, Slack, or other SNS subscribers)

This serverless approach provides centralized failure analysis across all your Spark platforms without requiring changes to individual pipelines. The following video demonstrates this integration:

A reference implementation of this solution is available in the Amazon EMR Utilities GitHub repository (documentation).

Solution 3 – Intelligent Dashboards: Use the Apache Spark troubleshooting agent with Kiro IDE to visualize account level application failures: what failed, why failed and how to fix

Understanding the health of your Spark workloads across multiple platforms requires consolidating data from Amazon EMR (both EC2 and Serverless) and AWS Glue. Teams typically build custom monitoring solutions by writing scripts to query multiple APIs, aggregate metrics, and generate reports which can be time consuming and require active maintenance.

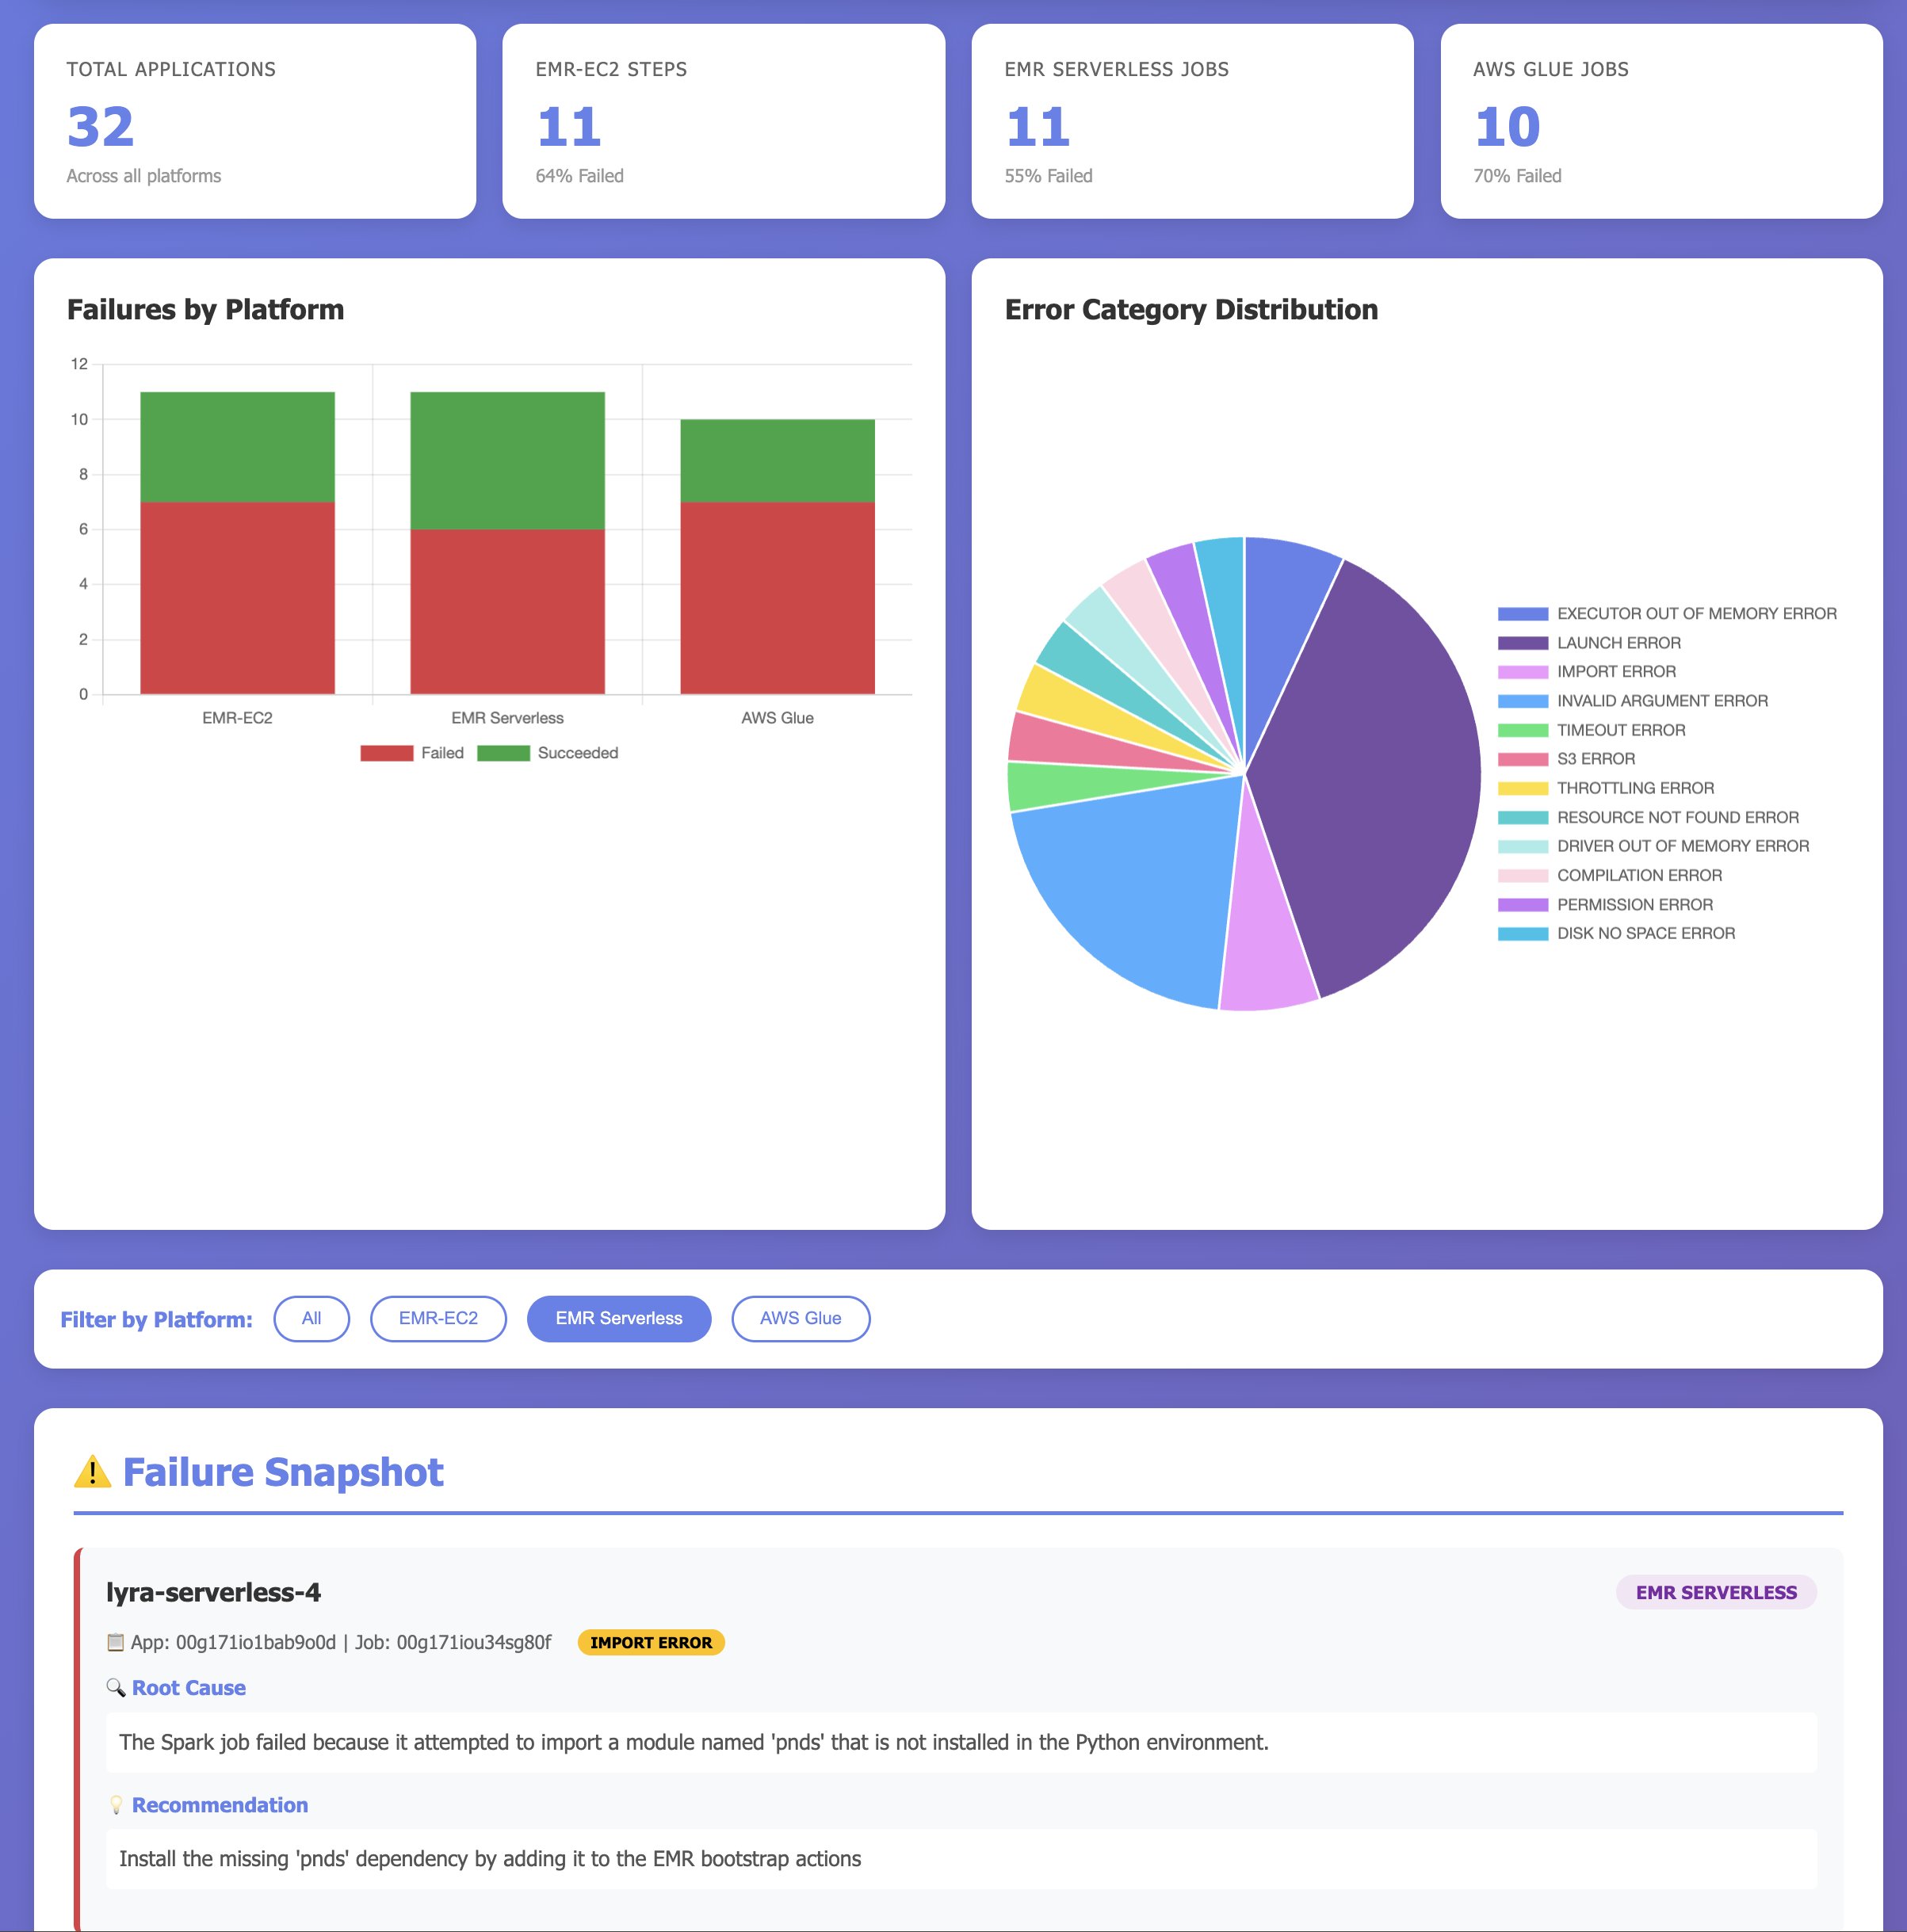
With Kiro IDE and the Apache Spark troubleshooting agent, you can build comprehensive monitoring dashboards conversationally. Instead of writing custom code to aggregate workload metrics, you can describe what you want to track, and the agent generates a complete dashboard showing overall performance metrics, error category distributions for failures, success rates across platforms, and critical failures requiring immediate attention. Unlike traditional dashboards that only show traditional KPIs and metrics on what application failed, this dashboard uses the Spark troubleshooting agent to provide insights to users on why the applications failed, and how they can be fixed. The following video demonstrates building a multi-platform monitoring dashboard using Kiro IDE:

The prompt used within the demo:

Build comprehensive monitoring dashboard for all of my Amazon EMR-EC2 steps, Amazon EMR Serverless jobs, and AWS Glue jobs for the last 30 days. Region: us-east-2. 
Execution Plan:
1. List all of my Spark applications across these services from the last 30 days. You can store any intermediate results in files in this folder as .json, but VALIDATE outputs before moving onto the next step. It's imperative to check the results before considering this done. You can write python script helpers to achieve this. Handle throttling and other exceptions gracefully. Make sure you cover all platforms: Amazon EMR-EC2, Amazon EMR Serverless, and AWS Glue.
2. Use the spark-troubleshooting-mcp to gather failure insights for each of my applications. Save this as .json as well. 
3. Then, use this information to help build the dashboard as HTML. Name the file dashboard.html.
Dashboard Requirements:
- Information from all of my Amazon EMR-EC2, Amazon EMR Serverless, and AWS Glue applications should be present
- overall success rates across platforms
- error category distributions for failures as a pie chart
- failures from last 30 days requiring attention with root causes and recommendations. Include error category and show the root causes and recommendations as they are returned by the spark-troubleshooting-mcp
- configuration comparisons per each platform. Configuration includes versions, worker types / DPUs, etc.

Clean up

To avoid incurring future AWS charges, delete the resources you created during this walkthrough:

  • Delete the AWS CloudFormation stack.
  • If you created an Amazon EventBridge rule for integration, delete those resources.

Conclusion

In this post, we demonstrated how the Apache Spark troubleshooting agent transforms hours of manual investigation into natural language conversations, significantly reducing troubleshooting time from hours to minutes and making Spark expertise accessible to all. By integrating natural language diagnostics into your existing development tools—whether Kiro CLI, Kiro IDE, or other MCP-compatible AI assistants—your teams can focus on building innovative applications instead of debugging failures.


Special thanks

A special thanks to everyone who contributed from engineering and science to the launch of the Spark troubleshooting agent and the remote MCP service: Tony Rusignuolo, Anshi Shrivastava, Martin Ma, Hirva Patel, Pranjal Srivastava, Weijing Cai, Rupak Ravi, Bo Li, Vaibhav Naik, XiaoRun Yu, Tina Shao, Pramod Chunduri, Ray Liu, Yueying Cui, Savio Dsouza, Kinshuk Pahare, Tim Kraska, Santosh Chandrachood, Paul Meighan and Rick Sears.

A special thanks to all of our partners who contributed to the launch of the Spark troubleshooting agent and the remote MCP service: Karthik Prabhakar, Suthan Phillips, Basheer Sheriff, Kamen Sharlandjiev, Archana Inapudi, Vara Bonthu, McCall Peltier, Lydia Kautsky, Larry Weber, Jason Berkovitz, Jordan Vaughn, Amar Wakharkar, Subramanya Vajiraya, Boyko Radulov and Ishan Gaur.

About the authors

Jake Zych

Jake is a Software Development Engineer at AWS Analytics. He has a deep interest in distributed systems and generative AI. In his spare time, Jake likes to create video content and play board games.

Maheedhar Reddy Chappidi

Maheedhar is a Senior Software Development Engineer at AWS Analytics. He is passionate about building fault-tolerant, reliable distributed systems at scale and generative AI applications for Data Integration. Outside of work, Maheedhar enjoys listening to podcasts and playing with his two-year-old child.

Vishal Kajjam

Vishal is a Senior Software Development Engineer at AWS Analytics. He is passionate about distributed computing and using ML/AI for designing and building end-to-end solutions to address customers’ data integration needs. In his spare time, he enjoys spending time with family and friends.

Arunav Gupta

Arunav is a Software Development Engineer at AWS Analytics. He is passionate about generative AI and orchestration and their uses in improving developer quality-of-life. In his free time, Arunav enjoys competing in a karting league and exploring new coffee shops in New York.

Wei Tang

Wei is a Software Development Engineer at AWS Analytics. She is strong developer with deep interests in solving recurring customer problems with distributed systems and AI/ML.

Andrew Kim

Andrew is a Software Development Engineer at AWS Analytics, with a deep passion for distributed systems architecture and AI-driven solutions, specializing in intelligent data integration workflows and cutting-edge feature development on Apache Spark. Andrew focuses on re-inventing and simplifying solutions to complex technical problems, and he enjoys creating web apps and producing music in his free time.

Jeremy Samuel

Jeremy is a Software Development Engineer at AWS Analytics. He has a strong interest in creating distributed systems and generative AI. In his spare time, he enjoys playing video games and listening to music.

Kartik Panjabi

Kartik is a Software Development Manager at AWS Analytics. His team builds generative AI features for the Data Integration and distributed system for data integration.

Shubham Mehta

Shubham is a Senior Product Manager at AWS Analytics. He leads generative AI feature development across services such as AWS Glue, Amazon EMR, and Amazon MWAA, using AI/ML to simplify and enhance the experience of data practitioners building data applications on AWS.

Vidyashankar Sivakumar

Vidyashankar is an applied scientist in the Data Processing and Experiences organization, where he works on DevOps agents that simplify and optimize the customer journey for AWS Big Data processing services such as Amazon EMR and AWS Glue. Outside of work, Vidyashankar enjoys listening to podcasts on current affairs, AI/ML, and AIOps, as well as following cricket.

Muhammad Ali Gulzar

Muhammad is an Amazon Scholar in the Data Processing Agents Science team, and an assistant professor in the Computer Science Department at Virginia Tech. Gulzar’s research interests lie at the intersection of software engineering and big data systems.

Mukul Prasad

Mukul is a Senior Applied Science Manager in the Data Processing and Experiences organization. He leads the Data Processing Agents Science team developing DevOps agents to simplify and optimize the customer journey in using AWS Big Data processing services including Amazon EMR, AWS Glue, and Amazon SageMaker Unified Studio. Outside of work, Mukul enjoys food, travel, photography, and Cricket.

Mohit Saxena

Mohit is a Senior Software Development Manager at AWS Analytics. He leads development of distributed systems with AI/ML-driven capabilities and Agents to simplify and optimize the experience of data practitioners that build big data applications with Apache Spark, Amazon S3 and data lakes/warehouses on the cloud.

Introducing Apache Iceberg materialized views in AWS Glue Data Catalog

Post Syndicated from Tomohiro Tanaka original https://aws.amazon.com/blogs/big-data/introducing-apache-iceberg-materialized-views-in-aws-glue-data-catalog/

Hundreds of thousands of customers build artificial intelligence and machine learning (AI/ML) and analytics applications on AWS, frequently transforming data through multiple stages for improved query performance—from raw data to processed datasets to final analytical tables. Data engineers must solve complex problems, including detecting what data has changed in base tables, writing and maintaining transformation logic, scheduling and orchestrating workflows across dependencies, provisioning and managing compute infrastructure, and troubleshooting failures while monitoring pipeline health. Consider an ecommerce company where data engineers need to continuously merge clickstream logs with orders data for analytics. Each transformation requires building robust change detection mechanisms, writing complex joins and aggregations, coordinating multiple workflow steps, scaling compute resources appropriately, and maintaining operational oversight—all while supporting data quality and pipeline reliability. This complexity demands months of dedicated engineering effort and ongoing maintenance, making data transformation costly and time-intensive for organizations seeking to unlock insights from their data.

To address those challenges, AWS announced a new materialized view capability for Apache Iceberg tables in the AWS Glue Data Catalog. The new materialized view capability simplifies data pipelines and accelerates data lake query performance. A materialized view is a managed table in the AWS Glue Data Catalog that stores pre-computed results of a query in Iceberg format that is incrementally updated to reflect changes to the underlying datasets. This alleviates the need to build and maintain complex data pipelines to generate transformed datasets and accelerate query performance. Apache Spark engines across Amazon Athena, Amazon EMR, and AWS Glue support the new materialized views and intelligently rewrite queries to use materialized views that speed up performance while reducing compute costs.

In this post, we show you how Iceberg materialized view works and how to get started.

How Iceberg materialized views work

Iceberg materialized views offer a simple, managed solution built on familiar SQL syntax. Instead of building complex pipelines, you can create materialized views using standard SQL queries from Spark, transforming data with aggregates, filters, and joins without writing custom data pipelines. Change detection, incremental updates, and monitoring source tables are automatically handled in the AWS Glue Data Catalog and refreshing materialized views as new data arrive, alleviating the need for manual pipeline orchestration. Data transformations run on fully managed compute infrastructure, removing the burden of provisioning, scaling, or maintaining servers.

The resulting pre-computed data is stored as Iceberg tables in an Amazon Simple Storage Service (Amazon S3) general purpose bucket, or Amazon S3 Tables buckets within the your account, making transformed data immediately accessible to multiple query engines, including Athena, Amazon Redshift, and AWS optimized Spark runtime. Spark engines across Athena, Amazon EMR, and AWS Glue support an automatic query rewrite functionality that intelligently uses materialized views, delivering automatic performance improvement for data processing jobs or interactive notebook queries.

In the following sections, we walk through the steps to create, query, and refresh materialized views.

Pre-requisite

To follow along with this post, you must have an AWS account.

To run the instruction on Amazon EMR, complete the following steps to configure the cluster:

  1. Launch an Amazon EMR cluster 7.12.0 or higher.
  2. SSH login to the primary node of your Amazon EMR cluster, and run the following command to start a Spark application with required configurations:
    spark-sql \
      --conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions \
      --conf spark.sql.catalog.glue_catalog=org.apache.iceberg.spark.SparkCatalog \
      --conf spark.sql.catalog.glue_catalog.type=glue \
      --conf spark.sql.catalog.glue_catalog.warehouse=s3://amzn-s3-demo-bucket/warehouse \
      --conf spark.sql.catalog.glue_catalog.glue.region=us-east-1 \
      --conf spark.sql.catalog.glue_catalog.glue.id=123456789012 \
      --conf spark.sql.catalog.glue_catalog.glue.account-id=123456789012 \
      --conf spark.sql.catalog.glue_catalog.client.region=us-east-1 \
      --conf spark.sql.catalog.glue_catalog.glue.lakeformation-enabled=true \
      --conf spark.sql.optimizer.answerQueriesWithMVs.enabled=true \
      --conf spark.sql.defaultCatalog=glue_catalog
      

To run the instruction on AWS Glue for Spark, complete the following steps to configure the job:

  1. Create an AWS Glue version 5.1 job or higher.
  2. Configure a job parameter
    1. Key: --conf
    2. Value: spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions
  3. Configure your job with the following script:
    from pyspark.sql import SparkSession
    
    
    spark = (
        SparkSession.builder \
            .config("spark.sql.extensions", "org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions")
            .config("spark.sql.catalog.glue_catalog", "org.apache.iceberg.spark.SparkCatalog")
            .config("spark.sql.catalog.glue_catalog.type", "glue")
            .config("spark.sql.catalog.glue_catalog.warehouse", "s3://amzn- -demo-bucket/warehouse")
            .config("spark.sql.catalog.glue_catalog.glue.region", "us-east-1")
            .config("spark.sql.catalog.glue_catalog.glue.id", "123456789012")
            .config("spark.sql.catalog.glue_catalog.glue.account-id", "123456789012")
    		.config("spark.sql.catalog.glue_catalog.client.region", "us-east-1")
            .config("spark.sql.catalog.glue_catalog.glue.lakeformation-enabled", "true")
            .config("spark.sql.optimizer.answerQueriesWithMVs.enabled", "true")
            .config("spark.sql.defaultCatalog", "glue_catalog")
            .getOrCreate()
    )

  4. Run the following queries using Spark SQL to set up a base table. In AWS Glue, you can run them through spark.sql("QUERY STATEMENT").
    CREATE DATABASE IF NOT EXIST iceberg_mv;
    
    USE iceberg_mv;
    
    CREATE TABLE IF NOT EXISTS base_tbl (
        id INT,
        customer_name STRING,
        amount INT,
        order_date DATE);
        
    INSERT INTO base_tbl VALUES (1, 'John Doe', 150, DATE('2025-12-01')), (2, 'Jane Smith', 200, DATE('2025-12-02')), (3, 'Bob Johnson', 75, DATE('2025-12-03'));
    
    SELECT * FROM base_tbl;

In the subsequent sections, we create a materialized view with this base table.

If you want to store your materialized views in Amazon S3 Tables instead of a general Amazon S3 bucket, refer to Appendix 1 at the end of this post for the configuration details.

Create a materialized view

To create a materialized view, run the following command:

CREATE MATERIALIZED VIEW mv
AS SELECT
    customer_name, 
    COUNT(*) as mv_order_count, 
    SUM(amount) as mv_total_amount 
FROM glue_catalog.iceberg_mv.base_tbl
GROUP BY customer_name;

After you create a materialized view, AWS Spark’s in-memory metadata cache needs time to populate with information about the new materialized view. During this cache population period, queries against the base table will run normally without using the materialized view. After the cache is fully populated (typically within tens of seconds), Spark automatically detects that the materialized view can satisfy the query and rewrites it to use the pre-computed materialized view instead, improving performance.

To see this behavior, run the following EXPLAIN command immediately after creating the materialized view:

EXPLAIN EXTENDED
SELECT customer_name, COUNT(*) as mv_order_count, SUM(amount) as mv_total_amount 
FROM base_tbl
GROUP BY customer_name;

The following output shows the initial result before cache population:

== Parsed Logical Plan ==
'Aggregate ['customer_name], ['customer_name, 'COUNT(1) AS mv_order_count#0, 'SUM('amount) AS mv_total_amount#1]
+- 'UnresolvedRelation [base_tbl] , [], false

== Analyzed Logical Plan ==
customer_name: string, mv_order_count: bigint, mv_total_amount: bigint
Aggregate [customer_name#8], [customer_name#8, count(1) AS mv_order_count#0L, sum(amount#9) AS mv_total_amount#1L]
+- SubqueryAlias glue_catalog.iceberg_mv.base_tbl
   +- RelationV2[id#7, customer_name#8, amount#9, order_date#10] glue_catalog.iceberg_mv.base_tbl glue_catalog.iceberg_mv.base_tbl

== Optimized Logical Plan ==
Aggregate [customer_name#8], [customer_name#8, count(1) AS mv_order_count#0L, sum(amount#9) AS mv_total_amount#1L]
+- RelationV2[customer_name#8, amount#9] glue_catalog.iceberg_mv.base_tbl

== Physical Plan ==
AdaptiveSparkPlan isFinalPlan=false
+- HashAggregate(keys=[customer_name#8], functions=[count(1), sum(amount#9)], output=[customer_name#8, mv_order_count#0L, mv_total_amount#1L], schema specialized)
   +- Exchange hashpartitioning(customer_name#8, 1000), ENSURE_REQUIREMENTS, [plan_id=19]
      +- HashAggregate(keys=[customer_name#8], functions=[partial_count(1), partial_sum(amount#9)], output=[customer_name#8, count#27L, sum#29L], schema specialized)
         +- BatchScan glue_catalog.iceberg_mv.base_tbl[customer_name#8, amount#9] glue_catalog.iceberg_mv.base_tbl (branch=null) [filters=, groupedBy=, pushedLimit=None] RuntimeFilters: []

In this initial execution plan, Spark scans the base_tbl directly (BatchScan glue_catalog.iceberg_mv.base_tbl) and runs aggregations (COUNT and SUM) on the raw data. This is the behavior before the materialized view metadata cache is populated.

After waiting approximately tens of seconds for the metadata cache population, run the same EXPLAIN command again. The following output shows the primary differences in the query optimization plan after cache population:

== Optimized Logical Plan ==
Aggregate [customer_name#97], [customer_name#97, coalesce(sum(mv_order_count#98L), 0) AS mv_order_count#72L, sum(mv_total_amount#99L) AS mv_total_amount#73L]
+- RelationV2[customer_name#97, mv_order_count#98L, mv_total_amount#99L] glue_catalog.iceberg_mv.mv

== Physical  Plan ==
AdaptiveSparkPlan isFinalPlan=false
+- HashAggregate(keys=[customer_name#97], functions=[sum(mv_order_count#98L), sum(mv_total_amount#99L)], output=[customer_name#97, mv_order_count#72L, mv_total_amount#73L], schema specialized)
   +- Exchange hashpartitioning(customer_name#97, 1000), ENSURE_REQUIREMENTS, [plan_id=51]
      +- HashAggregate(keys=[customer_name#97], functions=[partial_sum(mv_order_count#98L), partial_sum(mv_total_amount#99L)], output=[customer_name#97, sum#113L, sum#115L], schema specialized)
         +- BatchScan glue_catalog.iceberg_mv.mv[customer_name#97, mv_order_count#98L, mv_total_amount#99L] glue_catalog.iceberg_mv.mv (branch=null) [filters=, groupedBy=, pushedLimit=None] RuntimeFilters: []

After the cache is populated, Spark now scans the materialized view (BatchScan glue_catalog.iceberg_mv.mv) instead of the base table. The query has been automatically rewritten to read from the pre-computed aggregated data in the materialized view. The output specifically shows the aggregation functions now simply sum the pre-computed values (sum(mv_order_count) and sum(mv_total_amount)) rather than recalculating COUNT and SUM from raw data.

Create a materialized view with scheduling automatic refresh

By default, a newly created materialized view contains the initial query results. It’s not automatically updated when the underlying base table data changes. To keep your materialized view synchronized with the base table data, you can configure automatic refresh schedules. To enable automatic refresh, use the REFRESH EVERY clause when creating the materialized view. This clause accepts a time interval and unit, so you can specify how frequently the materialized view is updated.

The following example creates a materialized view that automatically refreshes every 24 hours:

CREATE MATERIALIZED VIEW mv
REFRESH EVERY 24 HOURS
AS SELECT
    customer_name, 
    COUNT(*) as mv_order_count, 
    SUM(amount) as mv_total_amount 
FROM glue_catalog.iceberg_mv.base_tbl
GROUP BY customer_name;

You can configure the refresh interval using any of the following time units: SECONDS, MINUTES, HOURS, or DAYS. Choose an appropriate interval based on your data freshness requirements and query patterns.

If you prefer more control over when your materialized view updates, or need to refresh it outside of the scheduled intervals, you can trigger manual refreshes at any time. We provide detailed instructions on manual refresh options, including full and incremental refresh, later in this post.

Query a materialized view

To query a materialized view on your Amazon EMR cluster and retrieve its aggregated data, you can use a standard SELECT statement:

SELECT * FROM mv;

This query retrieves all rows from the materialized view. The output shows the aggregated customer order counts and total amounts. The result displays three customers with their respective metrics:

-- Result
Jane Smith    1    200
Bob Johnson    1    75
John Doe    1    150

Additionally, you can query the same materialized view from Athena SQL. The following screenshot shows the same query run on Athena and the resulting output.

Refresh a materialized view

You can refresh materialized views using two refresh types: full refresh or incremental refresh. Full refresh re-computes the entire materialized view from all base table data. Incremental refresh processes only the changes since the last refresh. Full refresh is ideal when you need consistency or after significant data changes. Incremental refresh is preferred when you need immediate updates. The following examples show both refresh types.

To use full refresh, complete the following steps:

  1. Insert three new records into the base table to simulate new data arriving:
    INSERT INTO base_tbl VALUES 
    (4, 'Jane Smith', 350, DATE('2025-11-29')), 
    (5, 'Bob Johnson', 100, DATE('2025-11-30')), 
    (6, 'Kwaku Mensah', 40, DATE('2025-12-01'));

  2. Query the materialized view to verify it still shows the old aggregated values:
    SELECT * FROM mv;
    
    -- Result
    Jane Smith    1    200
    Bob Johnson    1    75
    John Doe    1    150

  3. Run a full refresh of the materialized view using the following command:
    REFRESH MATERIALIZED VIEW mv FULL;

  4. Query the materialized view again to verify the aggregated values now include the new records:
    SELECT * FROM mv;
    
    -- Result
    Jane Smith    2    550 // Updated
    Bob Johnson    2    175  // Updated
    John Doe    1    150
    Kwaku Mensah    1    40 // Added

To use incremental refresh, complete the following steps:

  1. Enable incremental refresh by setting the Spark configuration properties:
    SET spark.sql.optimizer.incrementalMVRefresh.enabled=true;

  2. Insert two additional records into the base table:
    INSERT INTO base_tbl VALUES 
    (7, 'Jane Smith', 120, DATE('2025-11-28')), 
    (8, 'Kwaku Mensah', 90, DATE('2025-12-02'));

  3. Run an incremental refresh using the REFRESH command without the FULL clause. To verify if incremental refresh is enabled, refer to Appendix 2 at the end of this post.
    REFRESH MATERIALIZED VIEW mv;

  4. Query the materialized view to confirm the incremental changes are reflected in the aggregated results:
    SELECT * FROM mv;
    
    --Result
    Jane Smith    3    670    3    3 // Updated
    Bob Johnson    2    175    2    2 
    John Doe    1    150    1    1
    Kwaku Mensah    2    130    2    2 // Updated

In addition to using Spark SQL, you can also trigger manual refreshes through AWS Glue APIs when you need updates outside your scheduled intervals. Run the following AWS CLI command:

$ aws glue start-materialized-view-refresh-task-run \
    --catalog-id <ACCOUNT_ID> \
    --database-name <DATABASE_NAME> \
    --table-name <MV_TABLE_NAME>

The AWS Lake Formation console displays refresh history for API-triggered updates. Open your materialized view to see the refresh type (INCREMENTAL or FULL), start and end time, status and so on:

You have learned how to use Iceberg materialized views to make your efficient data processing and queries. You created a materialized view using Spark on Amazon EMR, queried it from both Amazon EMR and Athena, and used two refresh mechanisms: full refresh and incremental refresh. Iceberg materialized views help you transform and optimize your data pipelines effortlessly.

Considerations

There are important aspects to consider for optimal usage of the capability:

  • We introduced new SQL syntax to manage materialized views in the AWS optimized Spark runtime engine only. These new SQL commands are available in Spark version 3.5.6 and above across Athena, Amazon EMR, and AWS Glue. Open source Spark is not supported.
  • Materialized views are eventually consistent with base tables. When source tables change, the materialized views are updated through background refresh processes as defined by users in the refresh schedule at creation. During the refresh window, queries directly accessing materialized views might see outdated data. However, customers who need immediate access to the most up-to-date datasets can run a manual refresh with a simple REFRESH MATERIALIZED VIEW SQL command.

Clean up

To avoid incurring future charges, clean up the resources you created during this walkthrough:

  1. Run the following commands to delete a materialized view and tables:
    DROP TABLE mv PURGE;
    -- Or, DROP MATERIALIZED VIEW mv;
    
    DROP TABLE base_tbl PURGE;
    -- If necessary, delete the database by DROP DATABASE iceberg_mv;

  2. For Amazon EMR, terminate the Amazon EMR cluster.
  3. For AWS Glue, delete the AWS Glue job.

Conclusion

This post demonstrated how Iceberg materialized views facilitate efficient data lake operations on AWS. The new materialized view capability simplifies data pipelines and improves query performance by storing pre-computed results that are automatically updated as base tables change. You can create materialized views using familiar SQL syntax, using both full and incremental refresh mechanisms to maintain data consistency. This solution alleviates the need for complex pipeline maintenance while providing seamless integration with AWS services like Athena, Amazon EMR, and AWS Glue. The automatic query rewrite functionality further optimizes performance by intelligently utilizing materialized views when applicable, making it a powerful tool for organizations looking to streamline their data transformation workflows and accelerate query performance.

Appendix 1: Spark configuration to use Amazon S3 Tables storing Apache Iceberg materialized views

As mentioned earlier in this post, materialized views are stored as Iceberg tables in Amazon S3 Tables buckets within your account. When you want to use Amazon S3 Tables as the storage location for your materialized views instead of a general Amazon S3 bucket, you must configure Spark with the Amazon S3 Tables catalog.

The difference from the standard AWS Glue Data Catalog configuration shown in the prerequisites section is the glue.id parameter format. For Amazon S3 Tables, use the format <account-id>:s3tablescatalog/<s3-tables-bucket-name> instead of just the account ID:

spark-sql \
  --conf spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions \
  --conf spark.sql.catalog.s3t_catalog=org.apache.iceberg.spark.SparkCatalog \
  --conf spark.sql.catalog.s3t_catalog.type=glue \
  --conf spark.sql.catalog.s3t_catalog.warehouse="s3://amzn-s3-demo-bucket/warehouse" \
  --conf spark.sql.catalog.s3t_catalog.glue.region="us-east-1" \
  --conf spark.sql.catalog.s3t_catalog.glue.id="123456789012:s3tablescatalog/amzn-s3-demo-table-bucket" \
  --conf spark.sql.catalog.s3t_catalog.glue.account-id=123456789012 \
  --conf spark.sql.catalog.s3t_catalog.client.region="us-east-1" \
  --conf spark.sql.catalog.s3t_catalog.glue.lakeformation-enabled=true \
  --conf spark.sql.optimizer.answerQueriesWithMVs.enabled=true \
  --conf spark.sql.defaultCatalog=s3t_catalog

After you configure Spark with these settings, you can create and manage materialized views using the same SQL commands shown in this post, and the materialized views are stored in your Amazon S3 Tables bucket.

Appendix 2: Verify refreshing a materialized view with Spark SQL

Run SHOW TBLPROPERTIES in Spark SQL to check which refresh method was used:

+-------------------------------+----------------------------------------------------------------------------------------------------------------------------------+
|key                            |value                                                                                                                             |
+-------------------------------+----------------------------------------------------------------------------------------------------------------------------------+
|IMV_ansiEnabled                |false                                                                                                                             |
|IMV_catalogInfo                |[{"catalogId":"123456789012","catalogName":"glue_catalog"}]                                                                       |
|IMV_mvCatalogID                |123456789012                                                                                                                      |
|IMV_mvNamespace                |iceberg_mv                                                                                                                        |
|IMV_region                     |us-east-1                                                                                                                         |
|IMV_sparkVersion               |3.5.6-amzn-1                                                                                                                      |
|current-snapshot-id            |5750703934418352571                                                                                                               |
|format                         |iceberg/parquet                                                                                                                   |
|format-version                 |2                                                                                                                                 |
|isMaterializedView             |true                                                                                                                              |
|lastRefreshType                |INCREMENTAL                                                                                                                       |
|subObjects                     |[{"Version":"4887707562550190856","DatabaseName":"iceberg_mv","Region":"us-east-1","CatalogId":"123456789012","Name":"base_tbl"}] |
|tableVersionToken              |*********(redacted)                                                                                                               |
|viewOriginalText               |SELECT\ncustomer_name, \nCOUNT(*) as mv_order_count, \nSUM(amount) as mv_total_amount \nFROM base_tbl\nGROUP BY customer_name     |
|viewVersionId                  |5750703934418352571                                                                                                               |
|viewVersionToken               |*********(redacted)                                                                                                               |
|write.parquet.compression-codec|zstd                                                                                                                              |
+-------------------------------+----------------------------------------------------------------------------------------------------------------------------------+

About the authors

Tomohiro Tanaka

Tomohiro Tanaka

Tomohiro is a Senior Cloud Support Engineer at AWS. He’s passionate about helping customers use Apache Iceberg for their data lakes on AWS. In his free time, he enjoys a coffee break with his colleagues and making coffee at home.

Leon Lin

Leon Lin

Leon is a Software Development Engineer at AWS, where he focuses on Apache Iceberg and Apache Spark development within the Open Data Analytics Engines team. He is also an active contributor to the open source Apache Iceberg project.

Noritaka Sekiyama

Noritaka Sekiyama

Noritaka is a Principal Big Data Architect with AWS Analytics services. He’s responsible for building software artifacts to help customers. In his spare time, he enjoys cycling on his road bike.

Mahesh Mishra

Mahesh Mishra

Mahesh is a Principal Product Manager with the AWS Analytics team. He works with many of AWS largest customers on emerging technology needs, and leads several data and analytics initiatives within AWS, including strong support for transactional data lakes.

Layth Yassin

Layth Yassin

Layth is a Software Development Engineer on the AWS Glue team. He’s passionate about tackling challenging problems at a large scale, and building products that push the limits of the field. Outside of work, he enjoys playing/watching basketball, and spending time with friends and family.

Introducing AWS Glue 5.1 for Apache Spark

Post Syndicated from Chiho Sugimoto original https://aws.amazon.com/blogs/big-data/introducing-aws-glue-5-1-for-apache-spark/

AWS Glue is a serverless, scalable data integration service that makes it simple to discover, prepare, move, and integrate data from multiple sources. AWS recently announced Glue 5.1, a new version of AWS Glue that accelerates data integration workloads in AWS. AWS Glue 5.1 upgrades the Spark engines to Apache Spark 3.5.6, giving you newer Spark release along with the newer dependent libraries so you can develop, run, and scale your data integration workloads and get insights faster.

In this post, we describe what’s new in AWS Glue 5.1, key highlights on Spark and related libraries, and how to get started on AWS Glue 5.1.

What’s new in AWS Glue 5.1

The following updates are in AWS Glue 5.1:

Runtime and library upgrades

AWS Glue 5.1 upgrades the runtime to Spark 3.5.6, Python 3.11, and Scala 2.12.18 with new improvements from the open source version. AWS Glue 5.1 also updates support for open table format libraries to Apache Hudi 1.0.2, Apache Iceberg 1.10.0, and Delta Lake 3.3.2 so you can solve advanced use cases around performance, cost, governance, and privacy in your data lakes.

Support for new Apache Iceberg features

AWS Glue 5.1 adds support for Apache Iceberg Materialized View, and Apache Iceberg format version 3.0. AWS Glue 5.1 also adds support for data writes into Iceberg and Hive tables with Spark-native fine-grained access control with AWS Lake Formation.

Apache Iceberg Materialized View is especially useful in cases where you need to accelerate frequently run queries on large data sets by pre-computing expensive aggregations. If you would like to learn more about Apache Iceberg materialized views, refer to Introducing Apache Iceberg materialized views in AWS Glue Data Catalog.

Apache Iceberg format version 3.0 is the latest Iceberg format version defined in Iceberg Table Spec. Following features are supported:

Create an Iceberg V3 format table

To create an Iceberg V3 format table, specify the format-version to 3 when creating the table. The following is a sample PySpark script: (replace amzn-s3-demo-bucket with your S3 bucket name):

from pyspark.sql import SparkSession

s3bucket = "amzn-s3-demo-bucket" 
database = "glue51_blog_demo" 
table_name = "iceberg_v3_table_demo"

spark = (
    SparkSession.builder
    .config("spark.sql.extensions", "org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions")
    .config("spark.sql.defaultCatalog", "glue_catalog")
    .config("spark.sql.catalog.glue_catalog", "org.apache.iceberg.spark.SparkCatalog")
    .config("spark.sql.catalog.glue_catalog.type", "glue")
    .config("spark.sql.catalog.glue_catalog.warehouse", f"s3://{s3bucket}/{database}/{table_name}/")
    .getOrCreate()
)

spark.sql(f"CREATE DATABASE IF NOT EXISTS {database}")

# Create Iceberg table with V3 format-version
spark.sql(f"""
    CREATE TABLE IF NOT EXISTS {database}.{table_name} (
        id int,
        name string,
        age int,
        created_at timestamp
    ) USING iceberg
    TBLPROPERTIES (
        'format-version'='3',
        'write.delete.mode'='merge-on-read'
    )
""")

To migrate from V2 format to V3, use ALTER TABLE ... SET TBLPROPERTIES to update the format-version. The following is a sample PySpark script:

spark.sql(f"ALTER TABLE {database}.{table_name} SET TBLPROPERTIES ('format-version'='3')")

You cannot rollback from V3 to V2, so you need to be careful to verify that all your Iceberg clients support Iceberg V3 format version. Once upgraded, older versions cannot correctly read newer format versions, as Iceberg table format versions are not forward-compatible.

Create a table with Row Lineage tracking enabled

To create a table with Row Lineage tracking enabled, set the table property row-lineage to true. The following is a sample PySpark script:

# Create Iceberg table with row-lineage-tracking
spark.sql(f"""
    CREATE TABLE IF NOT EXISTS {database}.{table_name} (
        id int,
        name string,
        age int,
        created_at timestamp
    ) USING iceberg
    TBLPROPERTIES (
        'format-version'='3',
        'row-lineage'='true',
        'write.delete.mode'='merge-on-read'
    )
""")

In tables with Row Lineage tracking enabled, row IDs are managed at the metadata level for tracking row modifications over time and auditing.

Extended support for AWS Lake Formation permissions

Fine-grained access control with Lake Formation has been supported through native Spark DataFrames and Spark SQL in Glue 5.0 for read operations. Glue 5.1 extends fine-grained access control for write operations.

Full-Table Access (FTA) control in Apache Spark were introduced for Apache Hive and Iceberg tables in Glue 5.0. Glue 5.1 extends FTA support for Apache Hudi tables and Delta Lake tables.

S3A by default

AWS Glue 5.1 uses S3A as the default S3 connector. This change aligns with the recent Amazon EMR adoption of S3A as the default connector and brings enhanced performance and advanced features to Glue workloads. For more details about the S3A connector’s capabilities and optimizations, see Optimize Amazon EMR runtime for Apache Spark with EMR S3A.

Note when migrating from Glue 5.0 to Glue 5.1, If both spark.hadoop.fs.s3a.endpoint and spark.hadoop.fs.s3a.endpoint.region are not set, the default region used by S3A is us-east-2. This may cause issues. To mitigate the issues caused by this change, set the spark.hadoop.fs.s3a.endpoint.region Spark configuration when using the S3A file system in AWS Glue 5.1.

Dependent library upgrades

AWS Glue 5.1 upgrades the runtime to Spark 3.5.6, Python 3.11, and Scala 2.12.18 with upgraded dependent libraries.

The following table lists dependency upgrades:

Dependency Version in AWS Glue 5.0 Version in AWS Glue 5.1
Spark 3.5.4 3.5.6
Hadoop 3.4.1 3.4.1
Scala 2.12.18 2.12.18
Hive 2.3.9 2.3.9
EMRFS 2.69.0 2.73.0
Arrow 12.0.1 12.0.1
Iceberg 1.7.1 1.10.0
Hudi 0.15.0 1.0.2
Delta Lake 3.3.0 3.3.2
Java 17 17
Python 3.11 3.11.14
boto3 1.34.131 1.40.61
AWS SDK for Java 2.29.52 2.35.5
AWS Glue Data Catalog Client 4.5.0 4.9.0
EMR DynamoDB Connector 5.6.0 5.7.0

The following are database connector (JDBC driver) upgrades:

Driver Connector version in AWS Glue 5.0 Connector version in AWS Glue 5.1
MySQL 8.0.33 8.0.33
Microsoft SQL Server 10.2.0 10.2.0
Oracle Databases 23.3.0.23.09 23.3.0.23.09
PostgreSQL 42.7.3 42.7.3
Amazon Redshift redshift-jdbc42-2.1.0.29 redshift-jdbc42-2.1.0.29

The following are Spark connector upgrades:

Driver Connector version in AWS Glue 5.0 Connector version in AWS Glue 5.1
Amazon Redshift 6.4.0 6.4.2
OpenSearch 1.2.0 1.2.0
MongoDB 10.3.0 10.3.0
Snowflake 3.0.0 3.1.1
BigQuery 0.32.2 0.32.2
AzureCosmos 4.33.0 4.33.0
AzureSQL 1.3.0 1.3.0
Vertica 3.3.5 3.3.5

Get started with AWS Glue 5.1

You can start using AWS Glue 5.1 through AWS Glue Studio, the AWS Glue console, the latest AWS SDK, and the AWS Command Line Interface (AWS CLI).

To start using AWS Glue 5.1 jobs in AWS Glue Studio, open the AWS Glue job and on the Job Details tab, choose the version Glue 5.1 – Supports Spark 3.5, Scala 2, Python 3.

To start using AWS Glue 5.1 on an AWS Glue Studio notebook or an interactive session through a Jupyter notebook, set 5.1 in the %glue_version magic:

%%glue_version 5.1

The following output shows that the session is set to use AWS Glue 5.1:

Setting Glue version to: 5.1

Spark Troubleshooting with Glue 5.1

To accelerate Apache Spark troubleshooting and job performance optimization for your Glue 5.1 ETL jobs, you can use the newly introduced Apache Spark troubleshooting agent. Traditional Spark troubleshooting requires extensive manual analysis of logs, performance metrics, and error patterns to identify root causes and optimization opportunities. The agent simplifies this process through natural language prompts, automated workload analysis, and intelligent code recommendations. The agent has three main components: an MCP-compatible AI assistant in your development environment for interaction, the MCP proxy for AWS that handles secure communication between your client and the MCP server, and an Amazon SageMaker Unified Studio managed MCP Server (preview) that provides specialized Spark troubleshooting and upgrade tools for Glue 5.1 jobs.

To set up the agent, follow the instructions to set up the resources and MCP configuration: Setup for Apache Spark Troubleshooting agent. Then, you can launch your preferred MCP client and use conversation to interact with the tools for troubleshooting.

The following is a demonstration on how you can use the Apache Spark troubleshooting agent with Kiro CLI to debug a Glue 5.1 job run.

For more information and video walkthroughs for how to use the Apache Spark troubleshooting agent, please refer to Apache Spark Troubleshooting agent for Amazon EMR.

Conclusion

In this post, we discussed the key features and benefits of AWS Glue 5.1. You can create new AWS Glue jobs on AWS Glue 5.1 or migrate your existing AWS Glue jobs to benefit from the improvements.

We would like to thank the support of numerous engineers and leaders who helped build Glue 5.1 to support customers with a performance optimized Spark runtime and deliver new capabilities.


About the authors

Chiho Sugimoto

Chiho is a Cloud Support Engineer on the AWS Big Data Support team. She is passionate about helping customers build data lakes using ETL workloads. She loves planetary science and enjoys studying the asteroid Ryugu on weekends.

Noritaka Sekiyama

Noritaka is a Principal Big Data Architect at the AWS Analytics product team. He’s responsible for designing new features in AWS products, building software artifacts, and providing architecture guidance to customers. In his spare time, he enjoys cycling on his road bike.

Peter Tsai

Peter is a Software Development Engineer at AWS, where he enjoys solving challenges in the design and performance of the AWS Glue runtime. In his leisure time, he enjoys hiking and cycling.

Bo Li

Bo Li is a Senior Software Development Engineer on the AWS Glue team. He is devoted to designing and building end-to-end solutions to address customers’ data analytic and processing needs with cloud-based, data-intensive and GenAI technologies.

Kartik Panjabi

Kartik is a Software Development Manager on the AWS Glue team. His team builds generative AI features for the Data Integration and distributed system for data integration.

Peter Manastyrny

Peter is a Product Manager focusing on data processing and data integration workloads at AWS. He is working on making AWS Glue the best tool for building and operating complex integrated data pipelines.

SAP data ingestion and replication with AWS Glue zero-ETL

Post Syndicated from Shashank Sharma original https://aws.amazon.com/blogs/big-data/sap-data-ingestion-and-replication-with-aws-glue-zero-etl/

Organizations increasingly want to ingest and gain faster access to insights from SAP systems without maintaining complex data pipelines. AWS Glue zero-ETL with SAP now supports data ingestion and replication from SAP data sources such as Operational Data Provisioning (ODP) managed SAP Business Warehouse (BW) extractors, Advanced Business Application Programming (ABAP), Core Data Services (CDS) views, and other non-ODP data sources. Zero-ETL data replication and schema synchronization writes extracted data to AWS services like Amazon Redshift, Amazon SageMaker lakehouse, and Amazon S3 Tables, alleviating the need for manual pipeline development. This creates a foundation for AI-driven insights when used with AWS services such as Amazon Q and Amazon Quick Suite, where you can use natural language queries to analyze SAP data, create AI agents for automation, and generate contextual insights across your enterprise data landscape.

In this post, we show how to create and monitor a zero-ETL integration with various ODP and non-ODP SAP sources.

Solution overview

The key component of SAP integration is the AWS Glue SAP OData connector, which is designed to work with the SAP data structures and protocols. The connector provides connectivity to ABAP-based SAP systems and adheres to the SAP security and governance frameworks. Key features of the AWS SAP connector include:

  • Uses OData protocol for data extraction from various SAP NetWeaver systems
  • Managed replication for complex SAP data models such as BW extractors (such as 2LIS_02_ITM) and CDS views (such as C_PURCHASEORDERITEMDEX)
  • Handles both ODP and non-ODP entities using the SAP change data capture (CDC) technology

The SAP connector works with both AWS Glue Studio or AWS managed replication with zero-ETL. Self-managed replication in AWS Glue Studio provides full control over data processing units, replication frequencies, adjusting price-performance, page size, data filters, destinations, file formats, data transformation, and writing your own code with selected runtime. AWS managed data replication in zero-ETL removes burden of custom configurations and provides an AWS managed alternative, allowing replication frequencies between 15 minutes to 6 days. The following solution architecture demonstrates the approaches of ingesting ODP and non-ODP SAP data using zero-ETL from various SAP sources and writing to Amazon Redshift, SageMaker lakehouse, and S3 Tables.

Change data capture for ODP sources

SAP ODP is a data extraction framework that enables incremental and data replication from SAP source systems to target systems. The ODP framework provides applications (subscribers) to request data from supported objects, such as BW extractors, CDS views, and BW objects, in an incremental manner.

AWS Glue zero-ETL data ingestion begins with executing a full initial load of entity data to establish the baseline dataset in the target system. After the initial full load is complete, SAP provisions a delta queue known as Operational Delta Queue (ODQ), which captures data changes, including deletions. The delta token is sent to the subscriber during the initial load and persisted within the zero-ETL internal state management system.

The incremental processing retrieves the last stored delta token from the state store, then sends a delta change request to SAP using this token using the OData protocol. The system processes returned INSERT/UPDATE/DELETE operations through the SAP ODQ mechanism and receives a new delta token from SAP even in scenarios where no records were modified. This new token is persisted in the state management system after successful ingestion. In error scenarios, the system preserves the existing delta token state, enabling retry mechanics without data loss.

The following screenshot illustrates a successful initial load followed by four incremental data ingestions on the SAP system.

Change data capture for non-ODP sources

Non-ODP structures are OData services that are not ODP enabled. These are APIs, functions, views, or CDS views that are exposed directly without the ODP framework. Data is extracted using this mechanism; however, incremental data extraction depends on the nature of the object. If the object, for example, contains a “last modified date” field, it is used to track changes and provide incremental data extraction.

AWS Glue zero-ETL provides out-of-the-box incremental data extraction for non-ODP OData services, provided the entity includes a field to track changes (last modified date or time). For such SAP services, zero-ETL provides two approaches for data ingestion: timestamp-based incremental processing and full load.

Timestamp-based incremental processing

Timestamp-based incremental processing uses customers’ configured timestamp fields in zero-ETL to optimize the data extraction process. The zero-ETL system establishes a starting timestamp that serves as the foundation for subsequent incremental processing operations. This timestamp, known as the watermark, is crucial for facilitating data consistency. The query construction mechanism builds OData filters based on timestamp comparisons. These queries extract records that are created or modified since the last successful processing execution. The system’s watermark management functionality maintains tracking of the highest timestamp value from each processing cycle and uses this information as the starting point for subsequent executions. The zero-ETL system performs an upsert on the target using the configured primary keys. This approach facilitates proper handling of updates while maintaining data integrity. After each successful target system update, the watermark timestamp is advanced, creating a reliable checkpoint for future processing cycles.

However, the timestamp-based approach has a limitation: it can’t track physical deletions because SAP systems don’t maintain deletion timestamps. In scenarios where timestamp fields are either unavailable or not configured, the system transitions to a full load with upsert processing.

Full load

The full load approach serves as both a standalone approach and a fallback mechanism when timestamp-based processing is not feasible. This method involves extracting the complete entity dataset during each processing cycle, making it suitable for scenarios where change tracking is not available or required. The extracted dataset is upserted in the target system. The upsert processing logic handles both new record insertions and updates to existing records.

When to choose incremental or full load

The timestamp-based incremental processing approach offers optimal performance and resource utilization for large datasets with frequent updates. Data transfer volumes are reduced through the selective transfer of only modified records, resulting in reductions in network traffic. This optimization directly translates into lower operational costs. The full load with upsert facilitates data synchronization in scenarios where incremental processing is not feasible.

Together, these approaches form a complete solution for zero-ETL integration with non-ODP SAP structures, addressing the diverse requirements of enterprise data integration scenarios. Organizations using these approaches should evaluate their specific use cases, data volumes, and performance requirements when choosing between the two approaches.The following diagram illustrates the SAP data ingestion workflow.

Flowchart diagram showing a data replication process. Starts with 'Entity Selected for Replication' at the top, flows to 'Initial Snapshot' step, then branches based on a decision 'Entity supports ODP?' into three paths: left path shows 'ODP Setup' leading to 'ODP Incremental Processing', middle path shows 'Timestamp based Incremental Setup' leading to 'Timestamp based Incremental Processing', and right path shows 'Full Load Setup' leading to 'Full Load Processing'. Each processing path includes an 'Integration Active?' decision point that loops back if yes, or flows to 'Error Recovery' at the bottom if no. The diagram uses rounded rectangles for processes, diamonds for decisions, and arrows showing flow direction.

Observing SAP zero-ETL integrations

AWS Glue maintains state management, logs, and metrics using Amazon CloudWatch logs. For instructions to configure observability, refer to Monitoring an integration. Make sure AWS Identity and Access Management (IAM) roles are configured for log delivery. The integration is monitored from both source ingestion and writing to the chosen target.

Monitoring source ingestion

The integration of AWS Glue zero-ETL with CloudWatch provides monitoring capabilities to track and troubleshoot the data integration processes. Through CloudWatch, you can access detailed logs, metrics, and events that help identify issues, monitor performance, and maintain operational health of your SAP data integrations. Let’s look at a few instances of success and error scenarios.

Scenario 1: Missing permissions on your role

This error occurred during a data integration process in AWS Glue when attempting to access SAP data. The connection encountered a CLIENT_ERROR with a 400 Bad Request status code, indicating that the role has missing permissions:

{
    "eventTimestamp": 1755031897157,
    "integrationArn": "arn:aws:glue:us-east-2:012345678901:integration:1da4dccd-96ce-4661-8ef1-bf216623d65f",
    "sourceArn": "arn:aws:glue:us-east-2:012345678901:connection/SAPOData-sap-glue-dev",
    "level": "ERROR",
    "messageType": "IngestionFailed",
    "details": {
        "loadType": "",
        "errorMessage": "You do not have the necessary permissions to access the glue connection. make sure that you have the correct IAM permissions to access AWS Glue resources.",
        "errorCode": "CLIENT_ERROR"
    }
}

Scenario 2: Broken delta links

The CloudWatch log indicates an issue with missing delta tokens during data synchronization from SAP to AWS Glue. The error occurs when attempting to access the SAP sales document item table FactsOfCSDSLSDOCITMDX through the OData service. The absence of delta tokens, which are needed for incremental data loading and tracking changes, has resulted in a CLIENT_ERROR (400 Bad Request) when the system tried to open the data extraction API RODPS_REPL_ODP_OPEN:

{
    "eventTimestamp": 1760700305466,
    "integrationArn": "arn:aws:glue:us-east-1:012345678901:integration:f62e1971-092c-46a3-ba88-d32f4c6cd649",
    "sourceArn": "arn:aws:glue:us-east-1:012345678901:connection/SAPOData-sap-glue-dev",
    "level": "ERROR",
    "messageType": "IngestionFailed",
    "details": {
        "tableName": "/sap/opu/odata/sap/Z_C_SALESDOCUMENTITEMDEX_SRV/FactsOfCSDSLSDOCITMDX",
        "loadType": "",
        "errorMessage": "Received an error from SAPOData: Could not open data access via extraction API RODPS_REPL_ODP_OPEN. Status code 400 (Bad Request).",
        "errorCode": "CLIENT_ERROR"
    }

Scenario 3: Client errors on SAP data ingestion

This CloudWatch log reveals a client exception scenario where the SAP entity EntityOf0VENDOR_ATTR is not located or accessed through the OData service. This CLIENT_ERROR occurs when the AWS Glue connector attempts to parse the response from the SAP system but fails, due to either the entity being non-existent in the source SAP system or the SAP instance being temporarily unavailable:

{
    "eventTimestamp": 1752676327649,
    "integrationArn": "arn:aws:glue:us-east-1:012345678901:integration:9f1acbc0-599f-47d2-8e84-e9779976af59",
    "sourceArn": "arn:aws:glue:us-east-1:012345678901:connection/SAPOData-sap-glue-dev",
    "level": "ERROR",
    "messageType": "IngestionFailed",
    "details": {
        "tableName": "/sap/opu/odata/sap/ZVENDOR_ATTR_SRV/EntityOf0VENDOR_ATTR",
        "loadType": "",
        "errorMessage": "Data read from source failed for entity /sap/opu/odata/sap/ZVENDOR_ATTR_SRV/EntityOf0VENDOR_ATTR using connector SAPOData; ErrorMessage: Glue connector returned client exception. The response from the connector application couldn't be parsed.",
        "errorCode": "CLIENT_ERROR"
    }
}

Monitoring target write

Zero-ETL employs monitoring mechanisms depending on the target system. For Amazon Redshift targets, it uses the svv_integration system view, which provides detailed information about integration status, job execution, and data movement statistics. When working with SageMaker lakehouse targets, zero-ETL tracks integration states through the zetl_integration_table_state table, which maintains metadata about synchronization status, timestamps, and execution details. Additionally, you can use CloudWatch logs to monitor the integration progress, capturing information about successful commits, metadata updates, and potential issues during the data writing process.

Scenario 1: Successful processing on SageMaker lakehouse target

The CloudWatch logs show successful data synchronization activity for the plant table using CDC mode. The first log entry (IngestionCompleted) confirms the successful completion of the ingestion process at timestamp 1757221555568, with a last sync timestamp of 1757220991999. The second log (IngestionTableStatistics) provides detailed statistics of the data modifications, showing that during this CDC sync 300 new records were inserted, 8 records were updated, and 2 records were deleted from the target database gluezetl. This level of detail helps in monitoring the volume and types of changes being propagated to the target system.

{
    "eventTimestamp": 1757221555568,
    "integrationArn": "arn:aws:glue:us-east-1:012345678901:integration:b7a1c69a-e180-4d27-b71d-5fcf196d9d2d",
    "sourceArn": "arn:aws:glue:us-east-1:012345678901:connection/mam301",
    "targetArn": "arn:aws:glue:us-east-1:012345678901:database/gluezetl",
    "level": "VERBOSE",
    "messageType": "IngestionCompleted",
    "details": {
        "tableName": "plant",
        "loadType": "CDC",
        "message": "Successfully completed ingestion",
        "lastSyncedTimestamp": 1757220991999,
        "consumedResourceUnits": "10"
    }
}

{
    "eventTimestamp": 1757222506936,
    "integrationArn": "arn:aws:glue:us-east-1:012345678901:integration:b7a1c69a-e180-4d27-b71d-5fcf196d9d2d",
    "sourceArn": "arn:aws:glue:us-east-1:012345678901:connection/mam301",
    "targetArn": "arn:aws:glue:us-east-1:012345678901:database/gluezetl",
    "level": "INFO",
    "messageType": "IngestionTableStatistics",
    "details": {
        "tableName": "plant",
        "loadType": "CDC",
        "insertCount": 300,
        "updateCount": 8,
        "deleteCount": 2
    }
}

Scenario 2: Metrics on Amazon SageMaker lakehouse target

The zetl_integration_table_state table in SageMaker lakehouse provides a view of integration status and data modification metrics. In this example, the table shows a successful integration for an SAP CDS view table with integration ID 62b1164f-5b85-45e4-b8db-9aa7ab841e98 in the testdb database. The record indicates that at timestamp 1733000485999, there were 10 insertion records processed (recent_insert_record_count: 10), with no updates or deletions (both counts at 0). This table serves as a monitoring tool, providing a centralized view of integration states and detailed statistics about data modifications, making it straightforward to track and verify data synchronization activities in the lakehouse.

+---+--------------------------------------+---------------+----------------------------------------------------------+-----------+--------+-----------------+-------------------------------+------------------------------+------------------------------+------------------------------+
| # | integration_id                       | target_database | table_name                                               | table_state | reason | last_updated_timestamp | recent_ingestion_record_count | recent_insert_record_count | recent_update_record_count | recent_delete_record_count |
+---+--------------------------------------+---------------+----------------------------------------------------------+-----------+--------+-----------------+-------------------------------+------------------------------+------------------------------+------------------------------+
| 2 | 62b1164f-5b85-45e4-b8db-9aa7ab841e98 | testdb        | _sap_opu_odata_sap_zcds_po_scl_new_srv_factsofzmmpurordsldex | SUCCEEDED |        | 1733000485999   | 10                            | 0                            | 0                            | 0                            |
+---+--------------------------------------+---------------+----------------------------------------------------------+-----------+--------+-----------------+-------------------------------+------------------------------+------------------------------+------------------------------+

Scenario 3: Redshift monitoring system uses two views to track zero-ETL integration status

svv_integration provides a high-level overview of the integration status, showing that integration ID 03218b8a-9c95-4ec2-81ad-dd4d5398e42a has successfully replicated 18 tables with no failures, and the last checkpoint was at transaction sequence 1761289852999.

+--------------------------------------+---------------+-----------+-----------------+-------------+----------------------------------------------+-------------------------+-----------------------+---------------+------------------+-----------------+-----------------+------------------+-----------------+-----------------+
| integration_id                       | target_database | source    | state           | current_lag | last_replicated_checkpoint                   | total_tables_replicated | total_tables_failed | creation_time | refresh_interval | source_database | is_history_mode | query_all_states | truncatecolumns | accept_invchars |
+--------------------------------------+---------------+-----------+-----------------+-------------+----------------------------------------------+-------------------------+-----------------------+---------------+------------------+-----------------+-----------------+------------------+-----------------+-----------------+
| 03218b8a-9c95-4ec2-81ad-dd4d5398e42a | test_case     | GlueSaaS  | CdcRefreshState | 771754      | {"txn_seq":"1761289852999","txn_id":"0"}     | 18                      | 0                     | 22:54.7       | 0                |                 | FALSE           | FALSE            | FALSE           | FALSE           |
+--------------------------------------+---------------+-----------+-----------------+-------------+----------------------------------------------+-------------------------+-----------------------+---------------+------------------+-----------------+-----------------+------------------+-----------------+-----------------+

svv_integration_table_state offers table-level monitoring details, showing the status of individual tables within the integration. In this case, the SAP material group text entity table is in Synced state, with its last replication checkpoint matching the integration checkpoint (1761289852999). The table currently shows 0 rows and 0 size, suggesting it’s newly created.

+--------------------------------------+---------------+-------------+--------------------------------------------------------------+-------------+----------------------------------------------+--------+-----------------------+------------+------------+-----------------+
| integration_id                       | target_database | schema_name | table_name                                                   | table_state | table_last_replicated_checkpoint             | reason | last_updated_timestamp | table_rows | table_size | is_history_mode |
+--------------------------------------+---------------+-------------+--------------------------------------------------------------+-------------+----------------------------------------------+--------+-----------------------+------------+------------+-----------------+
| 03218b8a-9c95-4ec2-81ad-dd4d5398e42a | test_case     | public      | /sap/opu/odata/sap/ZMATL_GRP_1_SRV/EntityOf0MATL_GRP_1_TEXT | Synced      | {"txn_seq":"1761289852999","txn_id":"0"}     |        | 23:03.8               | 0          | 0          | FALSE           |
+--------------------------------------+---------------+-------------+--------------------------------------------------------------+-------------+----------------------------------------------+--------+-----------------------+------------+------------+-----------------+

These views together provide a comprehensive monitoring solution for tracking both overall integration health and individual table synchronization status in Amazon Redshift.

Prerequisites

In the following sections, we walk through the steps required to set up an SAP connection and using that connection to create a zero-ETL integration. Before implementing this solution, you must have the following in place:

  • An SAP account
  • An AWS account with administrator access
  • Create an S3 Tables target and associate the S3 bucket sap_demo_table_bucket as a location of the database
  • Update AWS Glue Data Catalog settings using the following IAM policy for fine-grained access control of the Data Catalog for zero-ETL
  • Create an IAM role named zero_etl_bulk_demo_role, to be used by zero-ETL to access data from your SAP account
  • Create the secret zero_etl_bulk_demo_secret in AWS Secrets Manager to store SAP credentials

Create connection to SAP instance

To set up a connection to your SAP instance and provide data to access, complete the following steps:

  1. On the AWS Glue console, in the navigation pane under Data catalog, choose Connections, then choose Create Connection.
  2. For Data sources, select SAP OData, then choose Next.
  3. Enter the SAP instance URL.
  4. For IAM service role, choose the role zero_etl_bulk_demo_role (created as a prerequisite).
  5. For Authentication Type, choose the authentication type that you’re using for SAP.
  6. For AWS Secret, choose the secret zero_etl_bulk_demo_secret (created as a prerequisite).
  7. Choose Next.
  8. For Name, enter a name, such as sap_demo_conn.
  9. Choose Next.

Create zero-ETL integration

To create the zero-ETL integration, complete the following steps:

  1. On the AWS Glue console, in the navigation pane under Data catalog, choose Zero-ETL integrations, then choose Create zero-ETL integration.
  2. For Data source, select SAP OData, then choose Next.
  3. Choose the connection name and IAM role that you created in the previous step.
  4. Choose the SAP objects you want in your integration. The non-ODP objects are either configured for full load or incremental load, and ODP objects are automatically configured for incremental ingestion.
    1. For full load, leave Incremental update field set as No timestamp field selected.
    2. For incremental load, choose the edit icon for Incremental update field and choose a timestamp field.
    3. For ODP entities that offer delta token, the incremental update field is pre-selected, and no customer action is necessary.

      When making a new integration using the same SAP connection and entity in the data filter, you will not be able to select a different incremental update field from the first integration.
  5. For Target details, choose sap_demo_table_bucket (created as a prerequisite).
  6. For Target IAM role, choose sap_demo_role (created as a prerequisite).
  7. Choose Next.
  8. In the Integration details section, for Name, enter sap-demo-integration.
  9. Choose Next.
  10. Review the details and choose Create and launch integration.

The newly created integration is shown as Active in about a minute.

Clean up

To clean up your resources, complete the following steps. This process will permanently delete the resources created in this post; back up important data before proceeding.

  1. Delete the zero-ETL integration sap-demo-integration.
  2. Delete the S3 Tables target bucket sap_demo_table_bucket.
  3. Delete the Data Catalog connection sap_demo_conn.
  4. Delete the Secrets Manager secret zero_etl_bulk_demo_secret.

Conclusion

You can now transform your SAP data analytics without the complexity of traditional ETL processes. With AWS Glue zero-ETL, you can gain immediate access to your SAP data while maintaining its structure across S3 Tables, SageMaker lakehouse, and Amazon Redshift. Your teams can use ACID-compliant storage with time travel capabilities, schema evolution, and concurrent reads/writes at scale, while keeping data in cost-effective cloud storage. The solution’s AI capabilities through Amazon Q and SageMaker can help your business create on-demand data products, run text-to-SQL queries, and deploy AI agents using Amazon Bedrock and Quick Suite.

To learn more, refer to the following resources:

Ready to modernize your SAP data strategy? Explore AWS Glue zero-ETL and enrich your organization’s data analytics capabilities.


About the authors

Shashank Sharma

Shashank Sharma

Shashank is an Engineering Leader with over 15 years of experience in delivering data integration and replication solutions for first-party and third-party databases and SaaS for enterprise customers. He leads engineering for AWS Glue Zero-ETL and Amazon AppFlow.

Parth Panchal

Parth Panchal

Parth is an experienced Software Engineer with over 10 years of development experience, specializing in AWS Glue zero-ETL and SAP data integration solutions. He excels at diving deep into complex data replication challenges, delivering scalable solutions while maintaining high standards for performance and reliability.

Diego Lombardini

Diego Lombardini

Diego is an experienced Enterprise Architect with over 20 years’ experience across SAP technologies, specializing in SAP innovation and data and analytics. He has worked both as partner and as a customer, giving him a complete perspective on what it takes to sell, implement, and run systems and organizations. He is passionate about technology and innovation, focusing on customer outcomes and delivering business value.

Abhijeet Jangam

Abhijeet Jangam

Abhijeet is Data and AI leader with 20 years of SAP techno functional experience leading strategy and delivery across multiple industries. With dozens of SAP implementations experiences, he brings broad functional process knowledge along with deep technical expertise in application development, data engineering, and integrations.

Amazon FSx for NetApp ONTAP now integrates with Amazon S3 for seamless data access

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/amazon-fsx-for-netapp-ontap-now-integrates-with-amazon-s3-for-seamless-data-access/

Today, we’re announcing the ability to access your data in Amazon FSx for NetApp ONTAP file systems using Amazon Simple Storage Service (Amazon S3). With this capability, you can use your enterprise file data to augment generative AI applications with Amazon Bedrock Knowledge Bases for Retrieval Augmented Generation (RAG), train machine learning (ML) models with Amazon SageMaker, generate insights with Amazon S3 integrated third-party services, use comprehensive research capabilities in AI-powered business intelligence (BI) tools such as Amazon Quick Suite, and run analyses using Amazon S3 based cloud-native applications, all while your file data continues to reside in your FSx for NetApp ONTAP file system.

Amazon FSx for NetApp ONTAP is the first and fully AWS managed NetApp ONTAP file system in the cloud to migrate on-premises applications that rely on NetApp ONTAP or other network-attached storage (NAS) appliances to AWS without having to change how you manage your data. FSx for NetApp ONTAP provides the popular capabilities, high performance, and data management APIs of ONTAP file systems with the added benefits of the AWS Cloud, such as simplified management, on-demand scaling, and seamless integration with other AWS services.

Over the years, AWS has developed a broad range of industry-leading AI, ML, and analytics services and applications that work with data in Amazon S3 that organizations use to innovate faster, discover new insights, and make even better data-driven decisions. However, some organizations want to use these services with their enterprise file data stored in NetApp ONTAP or other NAS appliances.

How to get started
You can create and attach an S3 Access Point to your FSx for ONTAP file system using the Amazon FSx console, the AWS Command Line Interface (AWS CLI), or the AWS SDK.

I have an existing FSx for ONTAP file system demo-create-s3access which I created by following the steps in the Creating file systems in the FSx for ONTAP documentation. Using the Amazon FSx console I now choose the file system ID fs-0c45b011a7f071d70 to access the full details of the file system.

I’ll attach the access point to the volume of the file system. I choose the volume vol1 and then select Create S3 Access Point from the Actions dropdown menu.


I enter details such as the access point name, the type of file system user identity and the network configuration, then choose Create s3 Access Point to finalize the process.


After it’s created, the access point my-s3-accesspoint is ready to allow access to the file data stored in my file system demo-create-s3access from Amazon S3. Amazon Access Points are S3 endpoints that can be attached to Amazon FSx volumes and used to perform Amazon S3 object operations.


I can now bring proprietary data stored in the file system demo-create-s3access to Amazon S3 for use in applications that work with Amazon S3 while my file data continues to reside in the FSx for NetApp ONTAP file system using the access point my-s3-accesspoint (this data remains accessible through the file protocols).

For the walkthrough in this post, I’ll integrate with Quick Suite.

Integrating decades of enterprise file data with the latest AI powered BI tools on AWS
In the Quick Suite Console, in the left navigation pane, I choose Connections, then select Integrations. Before you begin, make sure that you have the correct permissions to the Amazon S3 AWS resource. You can control the AWS resources that Quick Suite can access by following the Amazon Quick Suite user guide.


After I’ve selected the Amazon S3 integration I enter my Amazon S3 Access Point alias as the S3 bucket URL, leave the rest of the information as default, then choose Create and continue.


I finalize the process by providing the Name of the knowledge base, the Description, then choose Create.


After the knowledge base has been created it’s automatically synchronized, it’s now available for interaction.


I want to learn more about the AWS European Sovereign Cloud so I’ve updated the file system (accessed through the S3 Access Point my-s3-accesspoin-iyytkgz83djdjj7abn3u711supfgkuse1b-ext-s3alias) with the AWS whitepaper on this topic. In the chat in Amazon Quick Suite. I start asking the first question “do we have any documentation on the europe sovereignty cloud?“. To answer my question, the chat agent accesses and analyzes various types of data sources I have permission to use, including uploaded files in my current conversation, spaces I have access to, knowledge bases from my integrations, and more.

When I verify the source, I see that the document I uploaded to my file system is listed as one of the sources.

Other use cases of Amazon S3 Access Points for Amazon FSx for NetApp ONTAP
Earlier, we looked at use cases such as connecting an organization’s proprietary file data to Amazon Quick Suite for advanced business intelligence. Additionally, Amazon S3 Access Points for Amazon FSx for NetApp ONTAP can be used to seamlessly integrate enterprise file data with comprehensive analytics services, such as Amazon Athena for serverless SQL queries or AWS Glue for ETL processing, to name a few.

Amazon S3 Access Points for Amazon FSx for NetApp ONTAP are also suitable for data access from serverless compute workloads that are cloud-native with containerized microservices that require flexible access to shared enterprise datasets, such as configuration files, reference data, content libraries, model artifacts, and application assets.

Now available
You can get started today using the Amazon FSx console, AWS CLI, or AWS SDK to attach Amazon S3 Access Points to your Amazon FSx for NetApp ONTAP file systems. The feature is available in the following AWS Regions: Africa (Cape Town), Asia Pacific (Hong Kong, Hyderabad, Jakarta, Melbourne, Mumbai, Osaka, Seoul, Singapore, Sydney, Tokyo), Canada (Central, Calgary), Europe (Frankfurt, Ireland, London, Milan, Paris, Spain, Stockholm, Zurich), Israel (Tel Aviv), Middle East (Bahrain, UAE), South America (Sao Paulo), US East (N. Virginia, Ohio), and US West (N. California Oregon). You’re billed by Amazon S3 for the requests and data transfer costs through your S3 Access Point, in addition to your standard Amazon FSx charges. Learn more on the Amazon FSx for NetApp ONTAP pricing page.

PS: Writing a blog post at AWS is always a team effort, even when you see only one name under the post title. In this case, I want to thank Luke Miller, for his expertise and generous help with technical guidance, which made this overview possible and comprehensive.

– Veliswa Boya.

Medidata’s journey to a modern lakehouse architecture on AWS

Post Syndicated from Mike Araujo original https://aws.amazon.com/blogs/big-data/medidatas-journey-to-a-modern-lakehouse-architecture-on-aws/

This post was co-authored by Mike Araujo Principal Engineer at Medidata Solutions.

The life sciences industry is transitioning from fragmented, standalone tools towards integrated, platform-based solutions. Medidata, a Dassault Systèmes company, is building a next-generation data platform that addresses the complex challenges of modern clinical research. In this post, we show you how Medidata created a unified, scalable, real-time data platform that serves thousands of clinical trials worldwide with AWS services, Apache Iceberg, and a modern lakehouse architecture.

Challenges with legacy architecture

As the Medidata clinical data repository expanded, the team recognized the shortcomings of the legacy data solution to provide quality data products to their customers across their growing portfolio of data offerings. Several data tenants began to erode. The following diagram shows Medidata’s legacy extract, transform, and load (ETL) architecture.

Built upon a series of scheduled batch jobs, the legacy system proved ill-equipped to provide a unified view of the data across the entire ecosystem. Batch jobs ran at different intervals, often requiring a sufficient degree of scheduling buffer to make sure upstream jobs completed within the expected window. As the data volume expanded, the jobs and their schedules continued to inflate, introducing a latency window between ingestion and processing for dependent consumers. Different consumers operating from various underlying data services further magnified the problem as pipelines had to be continuously built across a variety of data delivery stacks.

The expanding portfolio of pipelines began to overwhelm existing maintenance operations. With more operations, the opportunity for failure expanded and recovery efforts further complicated. Existing observability systems were inundated with operational data, and identifying the root cause of data quality issues became a multi-day endeavor. Increases in the data volume required scaling considerations across the entire data estate.

Additionally, the proliferation of data pipelines and copies of the data in different technologies and storage systems necessitated expanding access controls with enhanced security features to make sure only the correct users had access to the subset of data to which they were permitted. Making sure access control changes were correctly propagated across all systems added a further layer of complexity to consumers and producers.

Solution overview

With the advent of Clinical Data Studio (Medidata’s unified data management and analytics solution for clinical trials) and Data Connect (Medidata’s data solution for acquiring, transforming, and exchanging electronic health record (EHR) data across healthcare organizations), Medidata introduced a new world of data discovery, analysis, and integration to the life sciences industry powered by open source technologies and hosted on AWS. The following diagram illustrates the solution architecture.

Fragmented batch ETL jobs were replaced by real-time Apache Flink streaming pipelines, an open source, distributed engine for stateful processing, and powered by Amazon Elastic Kubernetes Service (Amazon EKS), a fully managed Kubernetes service. The Flink jobs write to Apache Kafka running in Amazon Managed Apache Kafka (Amazon MSK), a streaming data service that manages Kafka infrastructure and operations, before landing in Iceberg tables backed by the AWS Glue Data Catalog, a centralized metadata repository for data assets. From this collection of Iceberg tables, a central, single source of data is now accessible from a variety of consumers without additional downstream processing, alleviating the need for custom pipelines to satisfy the requirements of downstream consumers. Through these fundamental architectural changes, the team at Medidata solved the issues presented by the legacy solution.

Data availability and consistency

With the introduction of the Flink jobs and Iceberg tables, the team was able to deliver a consistent view of their data across the Medidata data experience. Pipeline latency was reduced from days to minutes, helping Medidata customers realize a 99% performance gain from the data ingestion to the data analytics layers. Due to Iceberg’s interoperability, Medidata users saw the same view of the data regardless of where they viewed that data, minimizing the need for consumer-driven custom pipelines because Iceberg could plug into existing consumers.

Maintenance and durability

Iceberg’s interoperability provided a single copy of the data to satisfy their use cases, so the Medidata team could focus its observation and maintenance efforts on a five-times smaller subset of operations than previously required. Observability was enhanced by tapping into the various metadata components and metrics exposed by Iceberg and the Data Catalog. Quality management transformed from cross-system traces and queries to a single analysis of unified pipelines, with an added benefit of point in time data queries thanks to the Iceberg snapshot feature. Data volume increases are handled with out-of-box scaling supported by the entire infrastructure stack and AWS Glue Iceberg optimization features that include compaction, snapshot retention, and orphan file deletion, which provide a set-and-forget experience for solving a number of common Iceberg frustrations, such as the small file problem, orphan file retention, and query performance.

Security

With Iceberg at the center of its solution architecture, the Medidata team no longer had to spend the time building custom access control layers with enhanced security features at each data integration point. Iceberg on AWS centralizes the authorization layer using familiar systems such as AWS Identity and Access Management (IAM), providing a single and durable control for data access. The data also stays entirely within the Medidata virtual private cloud (VPC), further reducing the opportunity for unintended disclosures.

Conclusion

In this post, we demonstrated how legacy universe of consumer-driven custom ETL pipelines can be replaced with a scalable, high-performant streaming lakehouses. By putting Iceberg on AWS at the center of data operations, you can have a single source of data for your consumers.

To learn more about Iceberg on AWS, refer to Optimizing Iceberg tables and Using Apache Iceberg on AWS.


About the authors

Mike Araujo

Mike is a Principal Engineer at Medidata Solutions, working on building a next generation data and AI platform for clinical data and trials. By using the power of open source technologies such as Apache Kafka, Apache Flink, and Apache Iceberg, Mike and his team have enabled the delivery of billions of clinical events and data transformations in near real time to downstream consumers, applications, and AI agents. His core skills focus on architecting and building big data and ETL solutions at scale as well as their integration in agentic workflows.

Sandeep Adwankar

Sandeep is a Senior Product Manager at AWS, who has driven feature launches across Amazon SageMaker, AWS Glue, and AWS Lake Formation. He has led initiatives in Amazon S3 Tables analytics, Iceberg compaction strategies, and AWS Glue Iceberg optimizations. His recent work focuses on generative AI and autonomous systems, including the AWS Glue Data Catalog model context protocol and Amazon Bedrock structured knowledge bases. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that accelerate their business outcomes.

Ian Beatty

Ian is a Technical Account Manager at AWS, where he specializes in supporting independent software vendor (ISV) customers in the healthcare and life sciences (HCLS) and financial services industry (FSI) sectors. Based in the Rochester, NY area, Ian helps ISV customers navigate their cloud journey by maintaining resilient and optimized workloads on AWS. With over a decade of experience building on AWS since 2014, he brings deep technical expertise from his previous roles as an AWS Architect and DevSecOps team lead for SaaS ISVs before joining AWS more than 3 years ago.

Ashley Chen

Ashley is a Solutions Architect at AWS based in Washington D.C. She supports independent software vendor (ISV) customers in the healthcare and life sciences industries, focusing on customer enablement, generative AI applications, and container workloads.

Introducing catalog federation for Apache Iceberg tables in the AWS Glue Data Catalog

Post Syndicated from Debika D original https://aws.amazon.com/blogs/big-data/introducing-catalog-federation-for-apache-iceberg-tables-in-the-aws-glue-data-catalog/

Apache Iceberg has become the standard choice of open table format for organizations seeking robust and reliable analytics at scale. However, enterprises increasingly find themselves navigating complex multi-vendor landscapes with disparate catalog systems. Managing data across these has become a major challenge for organizations operating in multi-vendor environments. This fragmentation drives significant operational complexity, particularly around access control and governance. Customers using AWS analytics services such as Amazon Redshift, Amazon EMR, Amazon Athena, Amazon SageMaker, and AWS Glue to analyze Iceberg tables in the AWS Glue Data Catalog want to get the same price-performance for workloads in remote catalogs. Simply migrating or replacing these remote catalogs isn’t practical, leaving teams to implement and maintain synchronization processes that continuously replicate metadata across systems, creating operational overhead, escalating costs, and risking data inconsistencies.

AWS Glue now supports catalog federation for remote Iceberg tables in the Data Catalog. With catalog federation, you can query remote Iceberg tables, stored in Amazon Simple Storage Service (Amazon S3) and cataloged in remote Iceberg catalogs, using AWS analytics engines and without moving or duplicating tables. After a remote catalog is integrated, AWS Glue always fetch the latest metadata in the background, so you always have access to the Iceberg metadata through your preferred AWS analytics services. This capability supports both coarse-grained access control and fine-grained permissions through AWS Lake Formation, giving you the flexibility on how and when remote Iceberg tables are shared with data consumers. With integration for Snowflake Polaris Catalog, Databricks Unity Catalog, and other custom catalogs supporting Iceberg REST specifications, you can federate to remote catalogs, discover databases and tables, configure access permissions, and begin querying remote Iceberg data.

In this post, we discuss how to get started with catalog federation for Iceberg tables in the Data Catalog.

Solution overview

Catalog federation uses the Data Catalog to communicate with remote catalog systems to discover catalog objects and Lake Formation to authorize access to their data in Amazon S3. When you query a remote Iceberg table, the Data Catalog discovers the latest table information in the remote catalog at query runtime, getting the table’s S3 location, current schema, and partition information. Your analytics engine (Athena, Amazon EMR, or Amazon Redshift) Your analytics engine (Athena, EMR, or Redshift) then uses this information to access Iceberg data files directly from Amazon S3. And Lake Formation manages access to the table by vending scoped credentials to the table data stored in Amazon S3, allowing the engines to apply fine-grained permissions to the federated table. This approach avoids metadata and data duplication while providing real-time access to remote Iceberg tables through your preferred AWS analytics engines.

The Data Catalog facilitates connectivity to remote catalog systems that support Apache Iceberg by establishing an AWS Glue connection with the remote catalog endpoint. You can connect the Data Catalog to remote Iceberg REST catalogs using OAuth2 or custom authentication mechanisms using an access token. During integration, administrators configure a principal (service account or identity) with the appropriate permissions to access resources in the remote catalog. The AWS Glue connection object uses this configured principal’s credentials to authenticate and access metadata in the remote catalog server. You can also connect the Data Catalog to remote catalogs that use a private link or proxy for isolating and restricting network access. After it’s connected, this integration uses the standardized Iceberg REST API specification to retrieve the most current table metadata information from these remote catalogs. AWS Glue onboards these remote catalogs as federated catalogs within its own catalog infrastructure, enabling unified metadata access across multiple catalog systems.

Lake Formation serves as the centralized authorization layer for managing user access to federated catalog resources. When users attempt to access tables and databases in federated catalogs, Lake Formation evaluates their permissions and enforces fine-grained access control policies.

Beyond metadata authorization, the catalog federation also manages secure access to the actual underlying data files. It accomplishes this through credential vending mechanisms that issue temporary, scope-limited credentials. AWS Glue federated catalogs work with your preferred AWS analytics engines and query services, enabling consistent metadata access and unified data governance across your analytics workloads.

In the following sections, we walk through the steps to integrate the Data Catalog with your remote catalog server:

  1. Set up an integration principal in the remote catalog and provide required access on catalog resources to this principal. Enable OAuth based authentication for the integration principal.
  2. Create a federated catalog in the Data Catalog using the AWS Glue connection. Create an AWS Glue connection that uses the credentials of the integration principal (in Step1) to connect to the Iceberg REST endpoint of the remote catalog. Configure an AWS Identity and Access Management (IAM) role with permission to S3 locations where the remote table data resides. In a cross-account scenario, make sure the bucket policy grants required access to this IAM role. This federated catalog mirrors the catalog object in your remote catalog server.
  3. Discover Iceberg tables in federated catalogs using Lake Formation or AWS Glue APIs. Query Iceberg tables using AWS analytics engines. During query operations, Lake Formation manages fine-grained permission on federated resources and credential vending to underlying data for the end-users.

Prerequisites

Before you begin, verify you have the following setup in AWS:

  • An AWS account.
  • The AWS Command Line Interface (AWS CLI) version 2.31.38 or later installed and configured.
  • An IAM admin role or user with appropriate permissions to the following services:
    • IAM
    • AWS Glue Data Catalog
    • Amazon S3
    • AWS Lake Formation
    • AWS Secrets manager
    • Amazon Athena
  • Create a data lake admin. For instructions, see Create a data lake administrator.

Set up authentication credentials in remote Iceberg catalog

Catalog federation to a remote Iceberg catalog uses the OAuth2 credentials of the principal configured with metadata access. This authentication mechanism allows the AWS Glue Data Catalog to access the metadata of various objects (such as databases, and tables) within the remote catalogs, based on the privileges associated with the principal. To support proper functionality, you must grant the principal with the necessary permissions to read the metadata of these objects. Generate the CLIENT_ID and CLIENT_SECRET to enable OAuth based authentication for the integration principal.

Create AWS Glue catalog federation using connection to remote Iceberg catalog

Create a federated catalog in the Data Catalog that mirrors a catalog object in the remote Iceberg catalog server and is used by the AWS Glue service to federate metadata queries such as ListDatabases, ListTables, and GetTable to the remote catalog. As data lake administrator, you can create a federated catalog in the Data Catalog using an AWS Glue connection object that is registered with AWS Lake Formation.

Configure data source connection for AWS Glue connection

Catalog federation uses an AWS Glue connection for metadata access when you provide authentication and Iceberg REST API endpoint configurations in the remote catalog. The AWS Glue connection supports OAuth2 or custom as the authentication method.

Connect using OAuth2 authentication

For the OAuth2 authentication method, you can provide a client secret either directly as input or stored in AWS Secrets Manager and used by the AWS Glue connection object during authentication. AWS Glue internally manages the token refresh upon expiration. To store the client secret in Secrets manager, complete the following steps:

  1. On the Secrets Manager console, choose Secrets in the navigation pane.
  2. Choose Store a new secret.
  3. Choose Other type of secret, provide the key name as USER_MANAGED_CLIENT_APPLICATION_CLIENT_SECRET, and enter the client secret value.
  4. Choose Next and provide a name for the secret.
  5. Choose Next and choose Store to save the secret.

Connect using custom authentication

For custom authentication, use Secrets Manager to store and retrieve the access token. This access token is created, refreshed, and managed by the customer’s application or system, providing proper control and management over the authentication process. To store the access token in Secrets Manager, complete the following steps:

  1. On the Secrets Manager console, choose Secrets in the navigation pane.
  2. Choose Store a new secret.
  3. Choose Other type of secret and provide the key name as BEARER_TOKEN with the value noted as the access token of the integration principal.
  4. Choose Next and provide a name for the secret.
  5. Choose Next and choose Store to save the secret.

Register AWS Glue connection with Lake Formation

Create an IAM role that Lake Formation can use to vend credentials and attach permission on S3 bucket prefixes where the Iceberg tables are stored. Optionally, if you’re using Secrets Manager to store the client secret or are using a network configuration, you can add permissions for those services to this role. For instruction, refer to Catalog federation to remote Iceberg catalogs.

Complete the following steps to register the connection:

  1. On the Lake Formation console, choose Catalogs in the navigation pane.
  2. Choose Create catalog and select the data source.
  3. Provide the federated catalog details:
    1. Name of the federated catalog.
    2. Catalog name in the remote catalog server and this needs to match the exact catalog name in remote catalog.
  4. Provide AWS Glue connection details. To reuse an existing connection, choose Select existing connection and choose the connection to reuse. For a first-time setup, choose Input new connection configuration and provide the following information:
    1. Provide the AWS Glue connection name.
    2. Provide the remote catalog Iceberg REST API endpoint.
    3. Specify the catalog object casing type. The connection can support uppercase objects through the object hierarchy or lowercase objects.
    4. Configure authentication parameters:
      1. For OAuth2: Provide the client ID and client secret directly or choose the secret where the client secret is stored, token authorization URL, and scope mapped to the credential.
      2. For custom: Provide the secret managed by Secrets Manager where the access token is stored.
      3. Network configuration: If you have a network and/or proxy setup, you can provide this information. Otherwise, leave this section as default.
  5. Register the connection with Lake Formation using the IAM role with access to the bucket where the remote table metadata and data is stored.
  6. Verify the connection by choosing Run test.
  7. After the test is successful, create the catalog.

You can now discover remote objects under the federated catalog. You can onboard other remote catalogs by reusing the existing connection configured to the same external catalog instance.

Query the federated catalog objects using AWS analytical engines

As the data lake administrator, you can now manage access control on databases and tables in a federated catalog using AWS Lake Formation. You can also use tag-based access control to scale your permission model by tagging the resource based on the access control mechanism.

After permissions are granted, an IAM principal or an IAM user can access the federated tables using AWS analytical services including Athena, Amazon Redshift, Amazon EMR, and Amazon SageMaker. Query the federated Iceberg table using Athena as shown in the following example.

Clean up

To avoid incurring ongoing charges, complete the following steps to clean up the resources created during this walkthrough:

  1. Delete the federated catalog in the Data Catalog:
    aws glue delete-catalog \
        --name <your-federated-catalog-name>

  2. Deregister the AWS Glue connection from Lake Formation:
    aws lakeformation deregister-resource \
        --resource-arn <your-glue-connector-arn>

  3. Revoke Lake Formation permissions (if any were granted):
    # List existing permissions first
    aws lakeformation list-permissions \
        --catalog-id <your-account-id> \
        --resource '{
            "Catalog": {}
        }'
    
    # Revoke permissions as needed
    aws lakeformation revoke-permissions \
        --principal '{
            "DataLakePrincipalIdentifier": "<principal-arn>"
        }' \
        --resource '{
            "Database": {
                "CatalogId": "<catalog-id>",
                "Name": "<database-name>"
            }
        }' \
        --permissions ["SELECT", "DESCRIBE"]

  4. Delete the AWS Glue connection:
    aws glue delete-connection \
        --connection-name <your-glue-connection-to-snowflake-account>

  5. Delete IAM roles and policies associated with Lake Formation and the AWS Glue connection:
    # Detach policies from the role
    aws iam detach-role-policy \
        --role-name <your-lakeformation-role-name> \
        --policy-arn <your-lakeformation-policy-arn>
    
    # Delete the custom policy
    aws iam delete-policy \
        --policy-arn <your-lakeformation-policy-arn>
    
    # Delete the role
    aws iam delete-role \
        --role-name <your-lakeformation-role-name>
    # Detach policies from the role
    aws iam detach-role-policy \
        --role-name <your-glue-connection-role-name> \
        --policy-arn <your-glue-connection-policy-arn>
    
    # Delete the custom policy
    aws iam delete-policy \
        --policy-arn <your-glue-connection-policy-arn>
    
    # Delete the role
    aws iam delete-role \
        --role-name <your-glue-connection-role-name>

  6. Delete the Secrets Manager secret:
    # Schedule secret for deletion (7-30 days)
    aws secretsmanager delete-secret \
        --secret-id <your-snowflake-secret>

This teardown guide doesn’t affect the actual metadata in the remote catalog server nor the data in S3 buckets. It only affects the federation configurations in the Data Catalog and Lake Formation. Any corresponding service principals or configurations in the remote catalog server must be addressed separately.

Make sure you follow the teardown steps in the specified order to avoid dependency conflicts. For example, an AWS Glue connection object can’t be deleted if an AWS Glue catalog object is associated with it.

Additionally, make sure you have the necessary permissions to delete these resources.

Conclusion

In this post, we explored how catalog federation addresses the growing challenge of managing Iceberg tables across multi-vendor catalog environments. We walked through the architecture, demonstrating how the Data Catalog communicates with remote catalog systems, including Snowflake Polaris Catalog, Databricks Unity Catalog, and custom Iceberg REST-compliant catalogs, with centralized authorization and credential vending for secure data access. We covered the setup process, including configuring authentication principals, creating federated catalogs using AWS Glue connections, to implementing fine-grained access controls and querying remote Iceberg tables directly from AWS analytics engines.

Catalog federation offers several advantages:

  • Query your Iceberg data where it lives while maintaining security, governance, and price-performance benefits of AWS analytics services
  • Remove operational overheads and costs to maintain synchronization processes
  • Avoid data duplication and inconsistencies
  • Get real-time access to up-to-date table schemas without migrating or replacing existing catalogs.

To learn more, refer to Catalog federation to remote Iceberg catalogs.


About the authors

Debika D

Debika D

Debika is a Senior Product Marketing Manager with Amazon SageMaker, specializing in messaging and go-to-market strategy for lakehouse architecture. She is passionate about all things data and AI.

Srividya Parthasarathy

Srividya Parthasarathy

Srividya is a Senior Big Data Architect on the AWS Lake Formation team. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.

Pratik Das

Pratik Das

Pratik is a Senior Product Manager with AWS Lake Formation. He is passionate about all things data and works with customers to understand their requirements and build delightful experiences. He has a background in building data-driven solutions and machine learning systems.

Accelerate data lake operations with Apache Iceberg V3 deletion vectors and row lineage

Post Syndicated from Ron Ortloff original https://aws.amazon.com/blogs/big-data/accelerate-data-lake-operations-with-apache-iceberg-v3-deletion-vectors-and-row-lineage/

Organizations building petabyte-scale data lakes face increasing challenges as their data grows. Batch updates and compliance deletes create a proliferation of positional delete files, slowing downstream data pipelines and driving up storage costs. Tracking data changes for audit trails and incremental processing requires custom, engine-specific implementations that add complexity and maintenance burden. As data volumes scale, these challenges compound, leaving data teams juggling custom solutions and increasing operational costs just to maintain data freshness and compliance.

Apache Iceberg V3 addresses these challenges with two new capabilities: deletion vectors and row lineage. AWS now delivers these capabilities across Apache Spark on Amazon EMR 7.12, AWS Glue, Amazon SageMaker notebooks, Amazon S3 Tables, and the AWS Glue Data Catalog, giving you a complete, integrated V3 experience without custom implementation. This means faster writes, lower storage costs, comprehensive audit trails, and efficient incremental processing, all working seamlessly across your entire data lake architecture.

In this post, we walk you through the new capabilities in Iceberg V3, explain how deletion vectors and row lineage address these challenges, explore real-world use cases across industries, and provide practical guidance on implementing Iceberg V3 features across AWS analytics, catalog, and storage services.

What’s new in Iceberg V3

Iceberg V3 introduces new capabilities and data types. Two key capabilities that address the challenges discussed earlier are deletion vectors and row lineage.

Deletion vectors replace positional delete files with an efficient binary format stored as Puffin files. Instead of creating separate delete files for each delete operation, the deletion vector consolidates these delete references to a single delete vector per data file, rather than a delete reference file per deleted row. During query execution, engines efficiently filter out deleted rows using these compact vectors, maintaining query performance while removing the need to merge multiple delete files.

This avoids write amplification from random batch updates and GDPR compliance deletes, significantly reducing the overhead of maintaining fresh data. High-frequency update workloads can see immediate improvements in write performance and reduced storage costs from fewer small delete files. Additionally, having fewer small delete files reduces table maintenance costs for compaction operations.

Row lineage enables precise change tracking at the row level with full auditability. Row lineage adds metadata fields to each data file that track when rows were created and last modified. The _row_id field uniquely identifies each row, and the _last_updated_sequence_number field tracks the snapshot when the row was last modified. These fields enable efficient change tracking queries without scanning entire tables, and they’re automatically maintained by the Iceberg specification without requiring custom code.

Before row lineage, change tracking in Iceberg provided only the net changes between snapshots, making it difficult to track individual record modifications. Row lineage metadata fields can now be queried to return all incremental changes, giving you full fidelity for auditing data modifications and regulatory compliance. For data transformations, your downstream systems can process changes incrementally, speeding up data pipelines and reducing compute costs for change data capture (CDC) workflows. Row lineage is engine agnostic, interoperable, and built into the Iceberg V3 specification, alleviating the need for custom, engine-specific change tracking implementations.

Real-world use cases

The new Iceberg V3 capabilities address critical challenges across multiple industries:

  • Marketing and advertising services organizations – You can now efficiently handle GDPR right-to-be-forgotten requests and regulatory compliance deletes without the write amplification that previously degraded pipeline performance. Row lineage provides complete audit trails for data modifications, meeting strict regulatory requirements for data governance.
  • Ecommerce platforms processing millions of product updates and inventory changes daily – You can maintain data freshness while reducing storage costs. Deletion vectors enable faster upsert operations, helping teams meet aggressive SLA requirements during peak shopping periods.
  • Healthcare and life sciences companies – You can track patient data modifications with precision for compliance purposes while efficiently processing large-scale genomic datasets. Row lineage provides the detailed change history required for clinical trial audits and regulatory submissions.
  • Media and entertainment providers managing large catalogs of user viewing data – You can efficiently process incremental changes for recommendation engines. Row lineage enables downstream analytics systems to process only changed records, reducing compute costs in incremental processing scenarios.

Get started with Iceberg V3

To take advantage of deletion vectors for optimized writes and row lineage for built-in change tracking in Iceberg V3, set the table property format-version = 3 during table creation. Alternatively, setting this property on an existing Iceberg V2 table atomically upgrades the table without data rewrites. Before creating or upgrading V3 tables, make sure the Iceberg engines in your solution are V3-compatible. Refer to Apache Iceberg V3 on AWS for more details.

Create a new V3 table with Apache Spark on Amazon EMR 7.12

The following code creates a new table named customer_data. Setting the table property format-version = 3 creates a V3 table. If the format-version table property is not explicitly set, a V2 table is created. V2 is currently the Iceberg default table version. Setting write.delete.mode, write.update.mode, and write.merge.mode to merge-on-read configures Spark to write deletion vectors for delete, update, or merge statements performed on the table.

CREATE TABLE customer_data (
customer_id bigint,
name string,
email string,
last_purchase timestamp,
total_spent decimal(10,2)
)
USING iceberg
TBLPROPERTIES (
'format-version' = '3',
'write.delete.mode' = 'merge-on-read',
'write.update.mode' = 'merge-on-read',
'write.merge.mode' = 'merge-on-read'
)

Run the following code to insert records into the customer_data table:

INSERT INTO customer_data VALUES
 (1, 'Alejandro Rosalez', '[email protected]', TIMESTAMP '2025-11-24 18:55:27', 42.97)
,(2, 'Akua Mansa', '[email protected]', TIMESTAMP '2025-11-24 17:55:27', 25.02)
,(3, 'Ana Carolina Silva','[email protected]', TIMESTAMP '2025-11-24 16:55:27', 43.67)
,(4, 'Arnav Desai','[email protected]', TIMESTAMP '2025-11-24 15:55:27', 98.32)
,(5, 'Carlos Salazar','[email protected]', TIMESTAMP '2025-11-24 12:55:27', 76.45)

Delete a record where customer_id = 5 to generate a delete file:

DELETE 
  FROM customer_data 
  WHERE customer_id = 5

Updating a record with the following update statement also generates a delete file:

UPDATE customer_data
  SET name = 'Mansa Akua' 
  WHERE customer_id = 2

The last part of this example queries the manifest’s metadata table to verify delete files were produced:

SELECT added_snapshot_id
      ,sum(added_delete_files_count) as added_delete_files_count 
FROM customer_data.manifests 
GROUP BY added_snapshot_id 
ORDER BY added_snapshot_id

This query will result in three records returned, as shown in the following screenshot. The added_delete_files_count for the first snapshot that inserts records should be 0. The next two snapshots for the corresponding delete and update statements should have 1 each for added_delete_files_count value.

Query row lineage for change tracking

Row lineage is automatically enabled on V3 tables. The following example includes row lineage metadata fields and an example of how to query table changes after a row lineage sequence number:

SELECT
customer_id,
name,
email,
_row_id,
_last_updated_sequence_number
FROM customer_data
WHERE _last_updated_sequence_number > 0
ORDER BY _last_updated_sequence_number, _row_id

Running this query after the previous insert, update, and delete statements returns four records, as shown in the following screenshot. The deleted record is removed. The _last_updated_sequence_number is 3 for the update to customer_id = 2.

Upgrade an existing V2 table

You can upgrade your existing V2 tables to V3 with the following command:

ALTER TABLE existing_customer_data
SET TBLPROPERTIES ('format-version' = '3')

When you upgrade a table from V2 to V3, several important operations occur atomically:

  • A new metadata snapshot is created atomically, resulting in no data loss.
  • Existing Parquet data files are reused without modification.
  • Row-lineage fields (_row_id and _last_updated_sequence_number) are added to the table metadata.
  • The next compaction operation will remove old V2 positional delete files. If new deletion vector files are generated before compaction runs, they will merge existing V2 positional delete files.
  • New modifications will automatically use V3’s deletion vector files.
  • The upgrade does not perform a historical backfill of row-lineage change tracking records.

The upgrade process is synchronous and completes in seconds for most tables. If the upgrade fails, an error message is returned immediately, and the table remains in its V2 state.

Getting the most from Iceberg V3

In this section, we share the key things we’ve learned from customers already using these features.

Know your workload pattern

Deletion vectors work best when you’re doing lots of writes, such as high-frequency updates, batch deletes, or CDC workloads making random non-append-only updates. If you’re writing more than you’re reading, deletion vectors will deliver immediate performance gains. To unlock these benefits, set your table to merge-on-read mode for delete, update, and merge operations.

Let AWS handle compaction

Enable automatic compaction through the Data Catalog or use S3 Tables (on by default). You will get hands-free optimization without building custom maintenance jobs. Deletion vectors produce fewer delete files than positional deletes in Iceberg V2. Given a similar pattern and amount of modified records, V3 compaction should be quicker and cost less than V2.

Understand the importance of row lineage when using the V2 changelog

With the Spark changelog procedure in Iceberg V2, if a row gets inserted and then deleted between snapshots, it disappears from your change feed—you never see it. Iceberg V3 row lineage captures both operations because _last_updated_sequence_number updates on each modification. This full fidelity is important for audit trails and regulatory compliance where you need to prove what happened to every record. Performance-wise, the V2 changelog requires scanning and merging delete files to compute changes—that’s compute you’re paying for on every read. V3 row lineage stores metadata fields directly on each row, so filtering by _last_updated_sequence_number is a simple metadata scan.

Test before you upgrade

Iceberg V3 upgrades are atomic and fast, but test in dev first. Make sure all your query engines support Iceberg V3 before upgrading shared tables—mixing V2 and V3 engines causes headaches. After upgrading, keep a few V2 snapshots around temporarily for time-travel queries while you validate performance.

Conclusion

Iceberg V3 support across AWS analytics, catalog, and storage services marks a significant advancement in data lake capabilities. By combining deletion vectors’ write optimization with row lineage’s comprehensive change tracking, you can build more efficient, auditable, and cost-effective data lakes at scale. The seamless interoperability across AWS services makes sure your data lake architecture remains flexible and future-proof.

To learn more about AWS support for Iceberg V3, refer to Using Apache Iceberg on AWS.

To learn more about building modern data lakes with Iceberg on AWS, refer to Analytics on AWS.


About the authors

Ron Ortloff

Ron Ortloff

Ron is a Principal Product Manager at AWS.

Scaling data governance with Amazon DataZone: Covestro success story

Post Syndicated from Jörg Janssen original https://aws.amazon.com/blogs/big-data/scaling-data-governance-with-amazon-datazone-covestro-success-story/

Covestro Deutschland AG, headquartered in Leverkusen, Germany, is a global leader in high-performance polymer materials and components. Since its spin-off from Bayer AG in 2015, Covestro has established itself as a key player in the chemical industry, with 48 production sites worldwide, €14.4 billion 2023 revenue, and 17,500 employees. Covestro’s core business focuses on developing innovative, sustainable solutions for products used in various aspects of daily life. The company offers materials for mobility, building and living, electrical and electronics sectors, in addition to sports and leisure, cosmetics, health, and the chemical industry. The company’s products, such as polycarbonates, polyurethanes, coatings, adhesives, and specialty elastomers, are important components in automotive, construction, electronics, and medical device industries.

To support this global operation and diverse product portfolio, Covestro adopted a robust data management solution. In this post, we show you how Covestro transformed its data architecture by implementing Amazon DataZone and AWS Serverless Data Lake Framework (SDLF), transitioning from a centralized data lake to a data mesh architecture. Through this strategic shift, teams can share and consume data while maintaining high quality standards through a consolidated data marketplace and business metadata glossary. The result: streamlined data access, better data quality, and stronger governance at scale that various producer and consumer teams can use to run data and analytics workloads at scale, enabling over 1,000 data pipelines and achieving a 70% reduction in time-to-market.

Business and data challenges

Prior to their transformation, Covestro operated with a centralized data lake managed by a single data platform team that handled the data engineering tasks. This centralized approach created several challenges: bottlenecks in project delivery because of limited engineering resources, complicated prioritization of use cases, and inefficient data sharing processes. The setup often resulted in unnecessary data duplication, which in turn slowed down time-to-market for new analytics initiatives, increased costs, and limited the ability of business units to act quickly on insights.The lack of visibility into data assets created significant operational challenges:

  • Teams could not find existing datasets, often recreating data already stored elsewhere
  • No clear understanding of data lineage or quality metrics
  • Difficulty in determining who owned specific data assets or who to contact for access
  • Absence of metadata and documentation about available datasets
  • Departments shared little knowledge about how they were using data

These visibility issues, combined with the lack of unified access controls, led to:

  • Siloed data initiatives across departments
  • Reduced trust in data quality
  • Inefficient use of resources
  • Delayed project timelines
  • Missed opportunities for cross-functional collaboration and insights

A strategic solution: Why Amazon DataZone and SDLF?

The challenges Covestro faced reflect deeper structural limitations of centralized data architectures. As Covestro scaled, central data teams often became bottlenecks, and lack of domain context led to fragmented quality, inconsistent standards, and poor collaboration. Instead of centralizing control, a data mesh gives ownership to the teams who generate and understand the data, while keeping the governance and interoperability consistent across the organization. This makes it well-suited for Covestro’s environment, which requires agility, scalability, and cross-team collaboration.

AWS Serverless Data Lake Framework (SDLF) is a solution to these challenges, providing a robust foundation for data mesh architectures. Traditional data lake implementations often centralize data ownership and governance, but with the flexible design of SDLF, organizations can build decentralized data domains that align with modern data mesh principles. The framework provides domain-oriented teams with the infrastructure, security controls, and operational patterns needed to own and manage their data products independently, while maintaining consistent governance across the organization. Through its modular architecture and infrastructure as code templates, SDLF accelerates the creation of domain-specific data products, so that Covestro’s teams can deploy standardized yet customizable data pipelines. This approach supports the key pillars of data mesh: domain-oriented decentralization, data as a product, self-serve infrastructure, and federated governance, providing Covestro with a practical path to overcome the limitations of traditional centralized architectures.

Amazon DataZone enhances the data mesh implementation through a unified experience for discovering and accessing data across decentralized domains. As a data management service, Amazon DataZone helps organizations catalog, discover, share, and govern data across organizational boundaries. It provides a central governance layer where organizations can establish data sharing agreements, manage access controls, and enable self-service data access while supporting security and compliance. While teams can use the SDLF framework to build and operate domain-specific data products, Amazon DataZone complements it with a searchable catalog enriched with metadata, business context, and usage policies, making data products easier to find, trust, and reuse.

Through the sharing capabilities of Amazon DataZone, domain teams can share their data products with other domains while maintaining granular access controls and governance policies, enabling cross-domain collaboration and data reuse. This integration means that domain teams can publish their SDLF-managed datasets to an Amazon DataZone catalog, so authorized consumers across the organization can discover and access them. Through the built-in governance capabilities built into Amazon DataZone, organizations can implement standardized data sharing workflows, check data quality, and enforce consistent access controls across their distributed data system, strengthening their data mesh architecture with robust data governance and democratization capabilities.Together, SDLF and Amazon DataZone provide Covestro with a comprehensive solution for implementing a modern data mesh architecture, enabling autonomous data domains to operate with consistent governance, seamless data sharing, and enterprise-wide data discovery.

Solution architecture and implementation

The following architecture illustrates the high-level design of the data mesh solution. The implementation used a comprehensive AWS solution built on AWS services to create a robust, scalable, and governed data mesh that serves multiple business domains across the Covestro organization.

Data domain foundation: Serverless Data Lake Framework

A key pillar of the implementation is the Serverless Data Lake Framework (SDLF), which provides the foundational infrastructure and security needed to support data mesh strategies. SDLF delivers the core building blocks for data domains such as Amazon S3 storage layers, built-in encryption with AWS KMS, IAM-based access control, and infrastructure as code (IaC) automation. By using these components, Covestro can deploy decentralized, domain-owned data products rapidly while maintaining consistent governance across the enterprise.

The framework uses Amazon Simple Storage Service (Amazon S3) as the primary data storage layer, delivering virtually unlimited scalability and eleven nines of durability for diverse data assets. The proposed S3 bucket architecture follows AWS Well-Architected principles, implementing a multi-tiered structure with distinct raw, staging, and analytics data zones. This layered approach helps different business domains to maintain data sovereignty (each domain owns and controls its data, while keeping accessibility patterns organization-wide).

Security is a fundamental aspect in Covestro’s data mesh implementation. SDLF automatically implements encryption at rest and in transit across data storage and processing components. AWS Key Management Service (AWS KMS) provides centralized key management, while carefully crafted AWS Identity and Access Management (IAM) roles enable resource isolation.

Data processing with AWS Glue

AWS Glue serves as the cornerstone of the data processing and transformation capabilities, offering serverless extract, transform, and load ETL services that automatically scale based on workload demands.

Covestro’s pre-existent centralized data lake was fed by more than 1,000 ingestion data pipelines interacting with a variety of source systems. To support the migration of existing ingestion and processing pipelines, Covestro developed reusable blueprints that included the development and security standards defined for the data mesh.Covestro released standardized patterns that teams can deploy across multiple domains while providing the flexibility needed for domain-specific requirements. These blueprints support diverse source systems, from traditional databases like Oracle, SQL Server, and MySQL to modern software as a service (SaaS) applications such as SAP C4C.

They also developed specialized blueprints for processing, standardizing, and cleaning ingested raw data. These blueprints store processed data in Apache Iceberg format, automatically saving metadata in the AWS Glue Data Catalog and providing built-in capabilities to handle schema evolution seamlessly.

Covestro relies on SDLF to quickly configure and deploy the blueprints as AWS Glue jobs inside the domain. With SDLF, teams deploy a data pipeline through a YAML configuration file, and the orchestration and management mechanisms of SDLF handle the rest. The solution includes comprehensive monitoring capabilities built on Amazon DynamoDB, providing real-time visibility into data pipeline health and performance metrics (when teams deploy a pipeline through SDLF, the system automatically integrates it with the monitoring setup).

Data quality with AWS Glue Data Quality

To achieve data reliability across domains, Covestro extended the capabilities of SDLF to incorporate AWS Glue Data Quality into data processing pipelines. This integration enables automated data quality checks as part of the standard data processing workflow. Thanks to the configuration-driven design of SDLF, data producers can implement quality controls either using recommended rules, which are automatically generated through data profiling, or applying their own domain-specific rules.

The integration provides data teams with the flexibility to define quality expectations while maintaining consistency in how quality checks are implemented at the pipeline level. The solution logs quality evaluation results, providing visibility into the data quality metrics for each data product. These elements are illustrated in the following figure.

Enterprise-ready access control with AWS Lake Formation

AWS Lake Formation integration with the Data Catalog supports the security and access control layer that makes the data mesh implementation enterprise-ready. Through Lake Formation, Covestro implemented fine-grained access controls that respect domain boundaries while enabling controlled cross-domain data sharing.

The service’s integration with IAM means that Covestro can implement role-based access patterns that align with their organizational structure, so users can access the data they need while keeping appropriate security boundaries.

Data democratization with Amazon DataZone

Amazon DataZone functions as the heart of the data mesh implementation. Deployed in a dedicated AWS account, it provides the data governance, discovery, and sharing capabilities that were missing in the previous centralized approach. DataZone offers a unified, searchable catalog enriched with business context, automated access controls, and standardized sharing workflows that enable true data democratization across the organization.

Through Amazon DataZone, Covestro established a comprehensive data catalog that helps business users across different domains to discover, understand, and request access to data assets without requiring deep technical expertise. The business glossary functionality supports consistent data definitions across domains, eliminating the confusion that often arises when different teams use different terminology for the same concepts.

Data product owners can use the integration of Amazon DataZone integration with AWS Lake Formation to grant or revoke cross-domain access to data, streamlining the data sharing process while supporting security and compliance requirements.

Managing cross-domain data pipeline dependencies

When implementing Covestro’s data mesh architecture on AWS, one of the most significant challenges was orchestrating data pipelines across multiple domains. The core question to address was “How can Data Domain A determine when a required dataset from Data Domain B has been refreshed and is ready for consumption?”.

In a data mesh architecture, domains maintain ownership of their data products while enabling consumption by other domains. This distributed model creates complex dependency chains where downstream pipelines must wait for upstream data products to complete processing before execution can begin.

To address this cross-domain dependency coordination, Covestro extended the SDLF with a custom dependency checker component that operates through both shared and domain-specific elements.

The shared components consist of two centralized Amazon DynamoDB tables located in a hub AWS account: one collecting successful pipeline execution logs from the domains, and another aggregating pipeline dependencies across the entire data mesh.

These domains deploy local components such as a dependency-tracking Amazon DynamoDB table and an AWS Step Functions state machine. The state machine checks prerequisites using centralized execution logs and integrates seamlessly as the first step in every SDLF-deployed pipeline, without additional configuration. The following diagram shows the process described.

To prevent circular dependencies that could create locks in the distributed orchestration system, Covestro implemented a sophisticated detection mechanism using Amazon Neptune. DynamoDB Streams automatically replicate dependency changes from domain tables to the central registry, triggering an AWS Lambda function that uses the Gremlin graph traversal language (using pygremlin) to construct, update, and analyze a directed acyclic graph (DAG) of the pipeline relationships, with native Gremlin functions detecting circular dependencies and sending automated notifications, as illustrated in the following diagram. This process continuously updates the graph to reflect any new pipeline dependencies or changes across the data mesh.

Operational excellence through infrastructure as code

Infrastructure as code (IaC) practices using AWS CloudFormation and the AWS Cloud Development Kit (AWS CDK) significantly improve the operational efficiency of the data mesh implementation. The infrastructure code is version-controlled in GitHub repositories, providing complete traceability and collaboration capabilities for data engineering teams. This approach uses a dedicated deployment account that uses AWS CodePipeline to orchestrate consistent deployments across multiple data mesh domains.

The centralized deployment model supports that infrastructure changes follow a standardized continuous integration and deployment (CI/CD) process, where code commits trigger automated pipelines that validate, test, and deploy infrastructure components to the appropriate domain accounts. Each data domain resides in its own separate set of AWS accounts (dev, qa, prod), and the centralized deployment pipeline respects these boundaries while enabling controlled infrastructure provisioning.

IaC enables the data mesh to scale horizontally when onboarding new domains, supporting the maintenance of consistent security, governance, and operational standards across the entire environment. Covestro provisions new domains quickly using proven templates, accelerating time-to-value for business teams.

Business impact and technical outcomes

The implementation of the data mesh architecture using Amazon DataZone and SDLF has delivered significant measurable benefits across Covestro’s organization:

Accelerated data pipeline development

  • 70% reduction in time-to-market for new data products through standardized blueprints
  • Successful migration of more than 1,000 data pipelines to the new architecture
  • Automated pipeline creation without manual coding requirements
  • Standardized approach and sharing across domains

Enhanced data governance and quality

  • Comprehensive business glossary implementation that supports consistent terminology
  • Automated data quality checks integrated into pipelines
  • End-to-end data lineage visibility across domains
  • Standardized metadata management through Apache Iceberg integration

Improved data discovery and access

  • Self-service data discovery portal through Amazon DataZone
  • Streamlined cross-domain data sharing with appropriate security controls
  • Reduced data duplication through improved visibility of existing assets
  • Efficient management of cross-domain pipeline dependencies

Operational efficiency

  • Decreased central data team bottlenecks through domain-oriented ownership
  • Reduced operational overhead through automated deployment processes
  • Improved resource utilization through elimination of redundant data processing
  • Enhanced monitoring and troubleshooting capabilities

The new infrastructure has fundamentally transformed how Covestro’s teams interact with data, enabling business domains to operate autonomously while upholding enterprise-wide standards for quality and governance. This has created a more agile, efficient, and collaborative data ecosystem that supports both current needs and future growth.

What’s next

As Covestro’s data platform continues to evolve, the focus is now to support domain teams to effectively built data products for cross domain analytics. In parallel, Covestro is actively working to improve data transparency with data lineage in Amazon DataZone through OpenLineage to support more comprehensive data traceability across a diverse set of processing tools and formats.

Conclusion

In this post, we showed you how Covestro transformed its data architecture transitioning from a centralized data lake to a data mesh architecture, and how this foundation will prove invaluable in supporting their journey toward becoming a more data-driven organization. Their experience demonstrates how modern data architectures, when properly implemented with the right tools and frameworks, can transform business operations and unlock new opportunities for innovation.

This implementation serves as a blueprint for other enterprises looking to modernize their data infrastructure while maintaining security, governance, and scalability. It shows that with careful planning and the right technology choices, organizations can successfully transition from centralized to distributed data architectures without compromising on control or quality.

For more on Amazon DataZone, see the Getting Started guide. To learn about the SDLF, see Deploy and manage a serverless data lake on the AWS Cloud by using infrastructure as code.


About the authors

Jörg Janssen

Jörg Janssen

Jörg serves as the Product Owner of the Covestro Data and Analytics Platform within Covestro IT & D. In this role, he bridges business requirements and technical execution, enabling data-driven innovation across the organization. With a strong background in chemistry and decades of IT experience, he plays a key role in advancing Covestro’s data strategy—empowering business units to develop innovative solutions in chemical manufacturing and operations, while ensuring effective data governance and stewardship.

Mousam Majhi

Mousam Majhi

Mousam is a Senior ProServe Cloud Architect focusing on Data & AI within AWS Professional Services. He works with Manufacturing and Travel, Transportation, and Logistics customers in DACH to achieve their business outcomes by leveraging data and AI powered solutions. Outside of work, Mousam enjoys hiking in the Bavarian Alps.

Giuseppe Perillo

Giuseppe Perillo

Giuseppe is a Data Architect at AWS Professional Services, specializing in data governance and the design of reliable, enterprise-grade data platforms. With a strong foundation in dimensional modeling, data warehousing, integration, and data quality, he helps customers build structured, trusted, and analytics-ready data environments.

Maddyzeth Ariza

Maddyzeth Ariza

Maddyzeth is a Data Architect at AWS Professional Services. She designs and implements scalable, cloud data solutions that support enterprise analytics, machine learning, and real-time processing. She specializes in serverless data architectures on AWS, including data lakes, data mesh, and enterprise-wide data governance. Outside of work, she enjoys exploring historic cities and landmarks across Europe.

Unlock real-time data insights with schema evolution using Amazon MSK Serverless, Iceberg, and AWS Glue streaming

Post Syndicated from Nitin Kumar original https://aws.amazon.com/blogs/big-data/unlock-real-time-data-insights-with-schema-evolution-using-amazon-msk-serverless-iceberg-and-aws-glue-streaming/

Efficient real-time synchronization of data within data lakes present challenges. Any data inaccuracies or latency issues can significantly compromise analytical insights and subsequent business strategies. Organizations increasingly require synchronized data in near real-time to extract actionable intelligence and respond promptly to evolving market dynamics. Additionally, scalability remains a concern for data lake implementations, which must accommodate expanding volumes of streaming data and maintain optimal performance without incurring high operational costs.

Schema evolution is the process of modifying the structure (schema) of a data table to accommodate changes in the data over time, such as adding or removing columns, without disrupting ongoing operations or requiring a complete data rewrite. Schema evolution is vital in streaming data environments for several reasons. Unlike batch processing, streaming pipelines operate continuously, ingesting data in real time from sources that are actively serving production applications. Source systems naturally evolve over time as businesses add new features, refine data models, or respond to changing requirements. Without proper schema evolution capabilities, even minor changes to source schemas can force streaming pipeline shutdowns, requiring developers to manually reconcile schema differences and rebuild tables.

Such disruptions reduce the core value proposition of streaming architectures—continuous, low-latency data processing. Organizations can maintain uninterrupted data flows and keep source systems evolving independently by using the seamless schema evolution provided by Apache Iceberg. This reduces operational friction and maintains the availability of real-time analytics and applications even as underlying data structures change.

Apache Iceberg is an open table format, delivering essential capabilities for streaming workloads, including robust schema evolution support. This critical feature enables table schemas to adapt dynamically as source database structures evolve, maintaining operational continuity. Consequently, when database columns undergo additions, removals, or modifications, the data lake accommodates these changes seamlessly without requiring manual intervention or risking data inconsistencies.

Our comprehensive solution showcases an end-to-end real-time CDC pipeline that enables immediate processing of data modifications from Amazon Relational Database Service (Amazon RDS) for MySQL, streaming altered records directly to AWS Glue streaming jobs using Amazon Managed Streaming for Apache Kafka (Amazon MSK) Serverless. These jobs continually process incoming changes and update Iceberg tables on Amazon Simple Storage Service (Amazon S3) so that the data lake reflects the current state of the operational database environment in real time. By using Apache Iceberg’s comprehensive schema evolution support, our ETL pipeline automatically adapts to database schema modifications, providing data lake consistency and currentness without manual intervention. This approach combines complete process control with instantaneous analytics on operational data, eliminating traditional latency, and future-proofs the solution to address evolving organizational data needs. The architecture’s inherent flexibility facilitates adaptation to diverse use cases requiring immediate data insights.

Solution overview

To effectively address streaming challenges, we propose an architecture using Amazon MSK Serverless, a comprehensive managed Apache Kafka service that autonomously provisions and scales computational and storage resources. This solution offers a frictionless mechanism for ingesting and processing streaming data without the complexity of capacity management. Our implementation uses Amazon MSK Connect with the Debezium MySQL connector to capture and stream database modifications in real time. Rather than employing traditional batch processing methodologies, we implement an AWS Glue streaming job that directly consumes data from Kafka topics, processes CDC events as they occur, and writes transformed data to Apache Iceberg tables on Amazon S3.

The workflow consists of the following:

  1. Data flows from Amazon RDS through Amazon MSK Connect using the Debezium MySQL connector to Amazon MSK Serverless. This represents a CDC pipeline that captures database changes from the relational database and streams them to Kafka.
  2. From Amazon MSK Serverless, the data then moves to AWS Glue job, which processes the data and stores it in Amazon S3 as Iceberg tables. The AWS Glue job interacts with the AWS Glue Data Catalog to maintain metadata about the datasets.
  3. Analyze the data using the serverless interactive query service Amazon Athena, which can be used to query the iceberg table created in Data Catalog. This allows for interactive data analysis without managing infrastructure.

The following diagram illustrates the architecture that we implement through this post. Each number corresponds to the preceding list and shows major components that you implement.

Prerequisites

Before getting started, make sure you have the following:

  • An active AWS account with billing enabled
  • An AWS Identity and Access Management (IAM) user with specific permissions to create and manage resources, such as a virtual private cloud (VPC), subnet, security group, IAM roles, NAT gateway, internet gateway, Amazon Elastic Compute Cloud (Amazon EC2) client, MSK Serverless, MSK Connector and its plugin AWS Glue job, and S3 buckets.
  • Sufficient VPC capacity in your chosen AWS Region.

For this post, we create the solution resources in the US East (N. Virginia) – us-east-1 Region using AWS CloudFormation templates. In the following sections, we show you how to configure your resources and implement the solution.

Configuring CDC and processing using AWS CloudFormation

In this post, you use the CloudFormation template vpc-msk-mskconnect-rds-client-gluejob.yaml. This template sets up the streaming CDC pipeline resources such as a VPC, subnet, security group, IAM roles, NAT, internet gateway, EC2 client, MSK Serverless, MSK Connect, Amazon RDS, S3 buckets, and AWS Glue job.

To create the solution resources for the CDC pipeline, complete the following steps:

  1. Launch the stack vpc-msk-mskconnect-rds-client-gluejob.yaml using the CloudFormation template:
  2. Provide the parameter values as listed in the following table.

    A B C
    1 Parameters Description Sample value
    2 EnvironmentName An environment name that is prefixed to resource names. msk-iceberg-cdc-pipeline
    3 DatabasePassword Database admin account password. ****
    4 InstanceType MSK client EC2 instance type. t2.micro
    5 LatestAmiId Latest AMI ID of Amazon Linux 3 for ec2 instance. You can use the default value. /aws/service/ami-amazon-linux-latest/al2023-ami-kernel-default-x86_64
    6 VpcCIDR IP range (CIDR notation) for this VPC. 10.192.0.0/16
    7 PublicSubnet1CIDR IP range (CIDR notation) for the public subnet in the first Availability Zone. 10.192.10.0/24
    8 PublicSubnet2CIDR IP range (CIDR notation) for the public subnet in the second Availability Zone. 10.192.11.0/24
    9 PrivateSubnet1CIDR IP range (CIDR notation) for the private subnet in the first Availability Zone. 10.192.20.0/24
    10 PrivateSubnet2CIDR IP range (CIDR notation) for the private subnet in the second Availability Zone. 10.192.21.0/24
    11 NumberOfWorkers Number of workers for AWS Glue streaming job. 3
    12 GlueWorkerType Worker type for AWS Glue streaming job. For example, G.1X. G.1X
    13 GlueDatabaseName Name of the AWS Glue Data Catalog database. glue_cdc_blogdb
    14 GlueTableName Name of the AWS Glue Data Catalog table. iceberg_cdc_tbl

The stack creation process can take approximately 25 minutes to complete. You can check the Outputs tab for the stack after the stack is created, as shown in the following screenshot.

Following the successful deployment of the CloudFormation stack, you now have a fully operational Amazon RDS database environment. The database instance contains the salesdb database with the customer table populated with 30 data records.

These records have been streamed to the Kafka topic through the Debezium MySQL connector implementation, establishing a reliable CDC pipeline. With this foundation in place, proceed to the next phase of the data architecture: near real-time data processing using the AWS Glue streaming job.

Run the AWS Glue streaming job

To transfer the data load from the Kafka topic (created by the Debezium MySQL connector for database table customer) to the Iceberg table, run the AWS Glue streaming job configured by the CloudFormation setup. This process will migrate all existing customer data from the source database table to the Iceberg table. Complete the following steps:

  1. On the CloudFormation console, choose the stack vpc-msk-mskconnect-rds-client-gluejob.yaml
  2. On the Outputs tab, retrieve the name of the AWS Glue streaming job from the GlueJobName row. In the following screenshot, the name is IcebergCDC-msk-iceberg-cdc-pipeline.
  3. On the AWS Glue console, choose ETL jobs in the navigation pane.
  4. Search for the AWS Glue job named IcebergCDC-msk-iceberg-cdc-pipeline.
  5. Choose the job name to open its details page.
  6. Choose Run to start the job. On the Runs tab, confirm if the job ran without failure.

You need to wait approximately 2 minutes for the job to process before continuing. This pause allows the jobrun to fully process records from the Kafka topic (initial load) and create the Iceberg table.

Query the Iceberg table using Athena

After the AWS Glue streaming job has successfully started and the Iceberg table has been created in the Data Catalog, follow these steps to validate the data using Athena:

  1. On the Athena console, navigate to the query editor.
  2. Choose the Data Catalog as the data source.
  3. Choose the database glue_cdc_blogdb.
  4. To validate the data, enter the following query to preview the data and find the total count:
    SELECT id, name, mktsegment FROM "glue_cdc_blogdb"."iceberg_cdc_tbl" order by id desc limit 40;
    
    SELECT count(*) as total_rows FROM "glue_cdc_blogdb"."iceberg_cdc_tbl";

    The following screenshot shows the output of the example query.

After performing the preceding steps, you’ve established a complete near real-time data processing pipeline by running an AWS Glue streaming job that transfers data from Kafka topics to an Apache Iceberg table, then verified the successful data migration by querying the results through Amazon Athena.

Upload incremental (CDC) data for further processing

Now that you’ve successfully completed the initial full data load, it’s time to focus on the dynamic aspects of the data pipeline. In this section, we explore how the system handles ongoing data modifications such as insertions, updates, and deletions in Amazon RDS for MySQL database. These changes won’t go unnoticed. Our Debezium MySQL connector stands ready to capture each modification event, transforming database changes into a continuous stream of data. Working in tandem with our AWS Glue streaming job, this architecture is designed to promptly process and propagate every change in our source database through our data pipeline.Let’s see this real-time data synchronization mechanism in action, demonstrating how our modern data infrastructure maintains consistency across systems with minimal latency. Follow these steps:

  1. On the Amazon EC2 console, access the EC2 instance that you created using the CloudFormation template named as KafkaClientInstance.
  2. Log in to the EC2 instance using AWS Systems Manager Agent (SSM Agent). Select the instance named as KafkaClientInstance and then choose Connect.
  3. Enter the following commands to insert the data into the RDS table. Use the same database password you entered when you created the CloudFormation stack.
    sudo su - ec2-user
    RDS_AURORA_ENDPOINT=`aws rds describe-db-instances --region us-east-1 | jq -r '.DBInstances[] | select(.DBName == "salesdb") | .Endpoint.Address'`
    mysql -f -u master -h $RDS_AURORA_ENDPOINT  --password

  4. Now perform the insert, update, and delete in the CUSTOMER table.
    use salesdb;
    
    INSERT INTO customer VALUES(31, 'Customer Name 31', 'Market segment 31');
    INSERT INTO customer VALUES(32, 'Customer Name 32', 'Market segment 32');
    
    UPDATE customer SET name='Customer Name update 29', mktsegment='Market segment update 29' WHERE id = 29;
    UPDATE customer SET name='Customer Name update 30', mktsegment='Market segment update 30' WHERE id = 30;
    
    DELETE FROM customer WHERE id = 27;
    DELETE FROM customer WHERE id = 28;
    

  5. Validate the data to verify the insert, update, and delete records in the Iceberg table from Athena, as shown in the following screenshot.

After performing the preceding steps, you’ve learned how our CDC pipeline handles ongoing data modifications by performing insertions, updates, and deletions in the MySQL database and verifying how these changes are automatically captured by Debezium MySQL connector, streamed through Kafka, and reflected in the Iceberg table in near real time.

Schema evolution: Adding new columns to the Iceberg table

The schema evolution mechanism in this implementation provides an automated approach to detecting and adding new columns from incoming data to existing Iceberg tables. Although Iceberg inherently supports robust schema evolution capabilities (including adding, dropping, and renaming columns, updating types, and reordering), this code specifically automates the column addition process for streaming environments. This automation uses Iceberg’s underlying schema evolution capabilities, which guarantee correctness through unique column IDs that ensure new columns never read existing values from another column. By handling column additions programmatically, the system reduces operational overhead in streaming pipelines where manual schema management would create bottlenecks. However, dropping and renaming columns, updating types, and reordering still required manual intervention.

When new data arrives through Kafka streams, the handle_schema_evolution() function orchestrates a four-step process to ensure seamless table schema updates.

  1. It analyzes the incoming batch DataFrame to infer its schema structure, cataloging all column names and their corresponding data types.
  2. It retrieves the existing Iceberg table’s schema from the AWS Glue catalog to establish a baseline for comparison.
  3. The system then performs a schema comparison using method compare_schemas() between batch schema with existing table schema.
    1. If the incoming frame contains fewer columns than the catalog table, no action is taken.
    2. It identifies any new columns present in the incoming data that don’t exist in the current table structure and returns a list of new columns that need to be added.
    3. New columns will be added at the last.
    4. Handle type evolution isn’t supported. If needed, you can handle the same at comment # Handle type evolution in the compare_schemas() method.
    5. If the destination table has columns that are dropped in the source table, it doesn’t drop those columns. If that is required for your use case, you can use drop column manually using ALTER TABLE ... DROP COLUMN.
    6. Renaming the column isn’t supported. To rename the column use case, manually evolve the schema using ALTER TABLE … RENAME COLUMN.
  4. Finally, if new columns are discovered, the function executes ALTER TABLE … ADD COLUMN statements to evolve the Iceberg table schema, adding the new columns with their appropriate data types.

This approach eliminates the need for manual schema management and prevents data pipeline failures that would typically occur when encountering unexpected fields in streaming data. The implementation also includes proper error handling and logging to track schema evolution events, making it particularly valuable for environments where data structures frequently change.

def infer_schema_from_batch(batch_df):
    """
    Infer schema from the batch DataFrame
    Returns a dictionary with column names and their inferred types
    """
    schema_dict = {}
    for field in batch_df.schema.fields:
        schema_dict[field.name] = field.dataType
    return schema_dict

def get_existing_table_schema(spark, table_identifier):
    """
    Read the existing table schema from the Iceberg table
    Returns a dictionary with column names and their types
    """
    try:
        existing_df = spark.table(table_identifier)
        schema_dict = {}
        for field in existing_df.schema.fields:
            schema_dict[field.name] = field.dataType
        return schema_dict
    except Exception as e:
        print(f"Error reading existing table schema: {e}")
        return {}

def compare_schemas(batch_schema, existing_schema):
    """
    Compare batch schema with existing table schema
    Returns a list of new columns that need to be added
    """
    new_columns = []
    
    for col_name, col_type in batch_schema.items():
        if col_name not in existing_schema:
            new_columns.append((col_name, col_type))
        elif existing_schema[col_name] != col_type:
            # Handle type evolution if needed
            print(f"Warning: Column {col_name} type mismatch - existing: {existing_schema[col_name]}, new: {col_type}")
    
    return new_columns

def spark_type_to_sql_string(spark_type):
    """
    Convert Spark DataType to SQL string representation for ALTER TABLE
    """
    type_mapping = {
        'IntegerType': 'INT',
        'LongType': 'BIGINT',
        'StringType': 'STRING',
        'BooleanType': 'BOOLEAN',
        'DoubleType': 'DOUBLE',
        'FloatType': 'FLOAT',
        'TimestampType': 'TIMESTAMP',
        'DateType': 'DATE'
    }
    
    type_name = type(spark_type).__name__
    return type_mapping.get(type_name, 'STRING')

def evolve_table_schema(spark, table_identifier, new_columns):
    """
    Alter the Iceberg table to add new columns
    """
    if not new_columns:
        return
    
    try:
        for col_name, col_type in new_columns:
            sql_type = spark_type_to_sql_string(col_type)
            alter_sql = f"ALTER TABLE {table_identifier} ADD COLUMN {col_name} {sql_type}"
            print(f"Executing schema evolution: {alter_sql}")
            spark.sql(alter_sql)
            print(f"Successfully added column {col_name} with type {sql_type}")
    except Exception as e:
        print(f"Error during schema evolution: {e}")
        raise e

def handle_schema_evolution(spark, batch_df, table_identifier):
    """
    schema evolution steps
    1. Infer schema from batch DataFrame
    2. Read existing table schema
    3. Compare schemas and identify new columns
    4. Alter table if schema evolved
    """
    # Step 1: Infer schema from batch DataFrame
    batch_schema = infer_schema_from_batch(batch_df)
    print(f"Batch schema: {batch_schema}")
    
    # Step 2: Read existing table schema
    existing_schema = get_existing_table_schema(spark, table_identifier)
    print(f"Existing table schema: {existing_schema}")
    
    # Step 3: Compare schemas
    new_columns = compare_schemas(batch_schema, existing_schema)
    
    # Step 4: Evolve schema if needed
    if new_columns:
        print(f"Schema evolution detected. New columns: {new_columns}")
        evolve_table_schema(spark, table_identifier, new_columns)
        return True
    else:
        print("No schema evolution needed")
        return False

In this section, we demonstrate how our system handles structural changes to the underlying data model by adding a new status column to the customer table and populating it with default values. Our architecture is designed to seamlessly propagate these schema modifications throughout the pipeline so that downstream analytics and processing capabilities remain uninterrupted while accommodating the enhanced data model. This flexibility is essential for maintaining a responsive, business-aligned data infrastructure that can evolve alongside changing organizational needs.

  1. Add a new status column to the customer table and populate it with default values as Green.
    use salesdb;
    
    ALTER TABLE customer ADD COLUMN status VARCHAR(20) NOT NULL;
    
    UPDATE customer SET status = 'Green';
    

  2. Use the Athena console to validate the data and schema evolution, as shown in the following screenshot.

When schema evolution occurs in an Iceberg table, the metadata.json file undergoes specific updates to track and manage these changes. In job when schema evolution detected, it ran the following query to evolve the schema for the Iceberg table.

ALTER TABLE glue_catalog.glue_cdc_blogdb.iceberg_cdc_tbl ADD COLUMN status string

We checked the metadata.json file in Amazon S3 for iceberg table location, and the following screenshot shows how the schema evolved.

We now explain how our implementation handles schema evolution by automatically detecting and adding new columns from incoming data streams to existing Iceberg tables. The system employs a four-step process that analyzes incoming data schemas, compares them with existing table structures, identifies new columns, and executes the necessary ALTER TABLE statements to evolve the schema without manual intervention, though certain schema changes still require manual handling.

Clean up

To clean up your resources, complete the following steps:

  1. Stop the running AWS Glue streaming job:
    1. On the AWS Glue console, choose ETL jobs in the navigation pane.
    2. Search for the AWS Glue job named IcebergCDC-msk-iceberg-cdc-pipeline.
    3. Choose the job name to open its details page.
    4. On the Runs tab, select running jobrun and choose Stop job run. Confirm that the job stopped successfully.
  2. Remove the AWS Glue database and table:
    1. On the AWS Glue console, choose Tables in the navigation pane, select iceberg_cdc_tbl, and choose Delete.
    2. Choose Databases in the navigation pane, select glue_cdc_blogdb, and choose Delete.
  3. Delete the CloudFormation stack vpc-msk-mskconnect-rds-client-gluejob.yaml.

Conclusion

This post showcases a solution that businesses can use to access real-time data insights without the traditional delays between data creation and analysis. By combining Amazon MSK Serverless, Debezium MySQL connector, AWS Glue streaming, and Apache Iceberg tables, the architecture captures database changes instantly and makes them immediately available for analytics through Amazon Athena. A standout feature is the system’s ability to automatically adapt when database structures change—such as adding new columns—without disrupting operations or requiring manual intervention. This eliminates the technical complexity typically associated with real-time data pipelines and provides business users with the most current information for decision-making, effectively bridging the gap between operational databases and analytical systems in a cost-effective, scalable way.


About the Authors

Nitin Kumar

Nitin Kumar

Nitin is a Cloud Engineer (ETL) at AWS, specializing in AWS Glue. With a decade of experience, he excels in aiding customers with their big data workloads, focusing on data processing and analytics. In his free time, he likes to watch movies and spend time with his family.

Shubham Purwar

Shubham Purwar

Shubham is an Analytics Specialist Solutions Architect at AWS. He helps organizations unlock the full potential of their data by designing and implementing scalable, secure, and high-performance analytics solutions on AWS. In his free time, Shubham loves to spend time with his family and travel around the world.

Noritaka Sekiyama

Noritaka Sekiyama

Noritaka is a Principal Big Data Architect on the AWS Glue team. He works based in Tokyo, Japan. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his road bike.

Visualize data lineage using Amazon SageMaker Catalog for Amazon EMR, AWS Glue, and Amazon Redshift

Post Syndicated from Shubham Purwar original https://aws.amazon.com/blogs/big-data/visualize-data-lineage-using-amazon-sagemaker-catalog-for-amazon-emr-aws-glue-and-amazon-redshift/

Amazon SageMaker offers a comprehensive hub that integrates data, analytics, and AI capabilities, providing a unified experience for users to access and work with their data. Through Amazon SageMaker Unified Studio, a single and unified environment, you can use a wide range of tools and features to support your data and AI development needs, including data processing, SQL analytics, model development, training, inference, and generative AI development. This offering is further enhanced by the integration of Amazon Q and Amazon SageMaker Catalog, which provide an embedded generative AI and governance experience, helping users work efficiently and effectively across the entire data and AI lifecycle, from data preparation to model deployment and monitoring.

With the SageMaker Catalog data lineage feature, you can visually track and understand the flow of your data across different systems and teams, gaining a complete picture of your data assets and how they’re connected. As an OpenLineage-compatible feature, it helps you trace data origins, track transformations, and view cross-organizational data consumption, giving you insights into cataloged assets, subscribers, and external activities. By capturing lineage events from OpenLineage-enabled systems or through APIs, you can gain a deeper understanding of your data’s journey, including activities within SageMaker Catalog and beyond, ultimately driving better data governance, quality, and collaboration across your organization.

Additionally, the SageMaker Catalog data lineage feature versions each event, so you can track changes, visualize historical lineage, and compare transformations over time. This provides valuable insights into data evolution, facilitating troubleshooting, auditing, and data integrity by showing exactly how data assets have evolved, and generates trust in data.

In this post, we discuss the visualization of data lineage in SageMaker Catalog and how capture lineage from different AWS analytics services such as AWS Glue, Amazon Redshift, and Amazon EMR Serverless automatically, and visualize it with SageMaker Unified Studio.

Solution overview

The generation of data lineage in SageMaker Catalog operates through an automated system that captures metadata and relationships between different data artifacts for AWS Glue, Amazon EMR, and Amazon Redshift. When data moves through various AWS services, SageMaker automatically tracks these movements, transformations, and dependencies, creating a detailed map of the data’s journey. This tracking includes information about data sources, transformations, processing steps, and final outputs, providing a complete audit trail of data movement and transformation.

The implementation of data lineage in SageMaker Catalog offers several key benefits:

  • Compliance and audit support – Organizations can demonstrate compliance with regulatory requirements by showing complete data provenance and transformation history
  • Impact analysis – Teams can assess the potential impact of changes to data sources or transformations by understanding dependencies and relationships in the data pipeline
  • Troubleshooting and debugging – When issues arise, the lineage system helps identify the root cause by showing the complete path of data transformation and processing
  • Data quality management – By tracking transformations and dependencies, organizations can better maintain data quality and understand how data quality issues might propagate through their systems

Lineage capture is automated using several tools in SageMaker Unified Studio. To learn more, refer to Data lineage support matrix.

In the following sections, we show you how to configure your resources and implement the solution. For this post, we create the solution resources in the us-west-2 AWS Region using an AWS CloudFormation template.

Prerequisites

Before getting started, make sure you have the following:

Configure SageMaker Unified Studio with AWS CloudFormation

The vpc-analytics-lineage-sus.yaml stack creates a VPC, subnet, security group, IAM roles, NAT gateway, internet gateway, Amazon Elastic Compute Cloud (Amazon EC2) client, S3 buckets, SageMaker Unified Studio domain, and SageMaker Unified Studio project. To create the solution resources, complete the following steps:

  1. Launch the stack vpc-analytics-lineage-sus using the CloudFormation template:
  2. Provide the parameter values as listed in the following table.

    Parameters Sample value
    DatazoneS3Bucket s3://datazone-{account_id}/
    DomainName dz-studio
    EnvironmentName sm-unifiedstudio
    PrivateSubnet1CIDR 10.192.20.0/24
    PrivateSubnet2CIDR 10.192.21.0/24
    PrivateSubnet3CIDR 10.192.22.0/24
    ProjectName sidproject
    PublicSubnet1CIDR 10.192.10.0/24
    PublicSubnet2CIDR 10.192.11.0/24
    PublicSubnet3CIDR 10.192.12.0/24
    UsersList analyst
    VpcCIDR 10.192.0.0/16

The stack creation process can take approximately 20 minutes to complete. You can check the Outputs tab for the stack after the stack is created.

Next, we prepare source data, setup the AWS Glue ETL Job, Amazon EMR Serverless Spark Job and Amazon Redshift Job to generate the lineage and capture lineage from Amazon SageMaker Unified Studio

Prepare data

The following is example data from our CSV files:

attendance.csv

EmployeeID,Date,ShiftStart,ShiftEnd,Absent,OvertimeHours
E1000,2024-01-01,2024-01-01 08:00:00,2024-01-01 16:22:00,False,3
E1001,2024-01-08,2024-01-08 08:00:00,2024-01-08 16:38:00,False,2
E1002,2024-01-23,2024-01-23 08:00:00,2024-01-23 16:24:00,False,3
E1003,2024-01-09,2024-01-09 10:00:00,2024-01-09 18:31:00,False,0
E1004,2024-01-15,2024-01-15 09:00:00,2024-01-15 17:48:00,False,1

employees.csv

EmployeeID,Name,Department,Role,HireDate,Salary,PerformanceRating,Shift,Location
E1000,Employee_0,Quality Control,Operator,2021-08-08,33002.0,1,Night,Plant C
E1001,Employee_1,Maintenance,Supervisor,2015-12-31,69813.76,5,Evening,Plant B
E1002,Employee_2,Production,Technician,2015-06-18,46753.32,1,Evening,Plant A
E1003,Employee_3,Admin,Supervisor,2020-10-13,52853.4,5,Night,Plant A
E1004,Employee_4,Quality Control,Manager,2023-09-21,55645.27,5,Evening,Plant A

Upload the sample data from attendance.csv and employees.csv to the S3 bucket specified in the previous CloudFormation stack (s3://datazone-{account_id}/csv/).

Ingest employee data in Amazon Relational Database Dervice (Amazon RDS) for MySQL table

On the CloudFormation console, open the stack vpc-analytics-lineage-sus and collect the Amazon RDS for MySQL database endpoint to use in the following commands to create a default employeedb database.

  1. Connect to Amazon EC2 instance with mysql package installation
  2. Run the following command to connect to the database
    >MySQL -u admin -h database-1.cuqd06l5efvw.us-west-2.rds.amazonaws.com -p

  3. Run the following command to create an employee table
    Use employeedb;
    
    CREATE TABLE employee (
      EmployeeID longtext,
      Name longtext,
      Department longtext,
      Role longtext,
      HireDate longtext,
      Salary longtext,
      PerformanceRating longtext,
      Shift longtext,
      Location longtext
    );

  4. Running the following command to insert rows.
    INSERT INTO employee (EmployeeID, Name, Department, Role, HireDate, Salary, PerformanceRating, Shift, Location) VALUES ('E1000', 'Employee_0', 'Quality Control', 'Operator', '2021-08-08', 33002.00, 1, 'Night', 'Plant C'), ('E1001', 'Employee_1', 'Maintenance', 'Supervisor', '2015-12-31', 69813.76, 5, 'Evening', 'Plant B'), ('E1002', 'Employee_2', 'Production', 'Technician', '2015-06-18', 46753.32, 1, 'Evening', 'Plant A'), ('E1003', 'Employee_3', 'Admin', 'Supervisor', '2020-10-13', 52853.40, 5, 'Night', 'Plant A'), ('E1004', 'Employee_4', 'Quality Control', 'Manager', '2023-09-21', 55645.27, 5, 'Evening', 'Plant A');

Capture lineage from AWS Glue ETL job and notebook

To demonstrate the lineage, we set up an AWS Glue extract, transform, and load (ETL) job to read the employee data from an Amazon RDS for MySQL table and the employee attendance data from Amazon S3, and join both datasets. Finally, we write the data to Amazon S3 and create the attendance_with_emp1 table in the AWS Glue Data Catalog.

Create and configure AWS Glue job for lineage generation

Complete the following steps to create your AWS Glue ETL job:

  1. On the AWS Glue console, create a new ETL job with AWS Glue version 5.0.
  2. Enable Generate lineage events and provide the domain ID (retrieve from the CloudFormation template output for DataZoneDomainid; it will have the format dzd_xxxxxxxx)
  3. Use the following code snippet in the AWS Glue ETL job script. Provide the S3 bucket (bucketname-{account_id}) used in the preceding CloudFormation stack.
    from pyspark.sql import SparkSession
    from pyspark.sql import SparkSession, DataFrame
    from pyspark.sql.functions import *
    from pyspark.sql.types import *
    from pyspark import SparkContext
    from pyspark.sql import SparkSession
    import sys
    import logging
    
    
    spark = SparkSession.builder.appName("lineageglue").enableHiveSupport().getOrCreate()
     
    connection_details = glueContext.extract_jdbc_conf(connection_name="connectionname")
    
    employee_df = spark.read.format("jdbc").option("url", "jdbc:MySQL://dbhost:3306/database_name").option("dbtable", "employee").option("user", connection_details['user']).option("password", connection_details['password']).load()
    
    s3_paths = {
    'absent_data': 's3://bucketname-{account_id}/csv/attendance.csv'
    }
    absent_df = spark.read.csv(s3_paths['absent_data'], header=True, inferSchema=True)
    
    joined_df = employee_df.join(absent_df, on="EmployeeID", how="inner")
    
    joined_df.write.mode("overwrite").format("parquet").option("path", "s3://datazone-{account_id}/attendanceparquet/").saveAsTable("gluedbname.tablename")

  4. Choose Run to start the job.
  5. On the Runs tab, confirm the job ran without failure.
  6. After the job has executed successfully, navigate to the SageMaker Unified Studio domain.
  7. Choose Project and under Overview, choose Data Sources.
  8. Select the Data Catalog source (accountid-AwsDataCatalog-glue_db_suffix-default-datasource).
  9. On the Actions dropdown menu, choose Edit.
  10. Under Connection, enable Import data lineage.
  11. In the Data Selection section, under Table Selection Criteria, provide a table name or use * to generate lineage.
  12. Update the data source and choose Run to create an asset called attendance_with_emp1 in SageMaker Catalog.
  13. Navigate to Assets, choose the attendance_with_emp1 asset, and navigate to the LINEAGE section.

The following lineage diagram shows an AWS Glue job that integrates data from two sources: employee information stored in Amazon RDS for MySQL and employee absence records stored in Amazon S3. The AWS Glue job combines these datasets through a join operation, then creates a table in the Data Catalog and registers it as an asset in SageMaker Catalog, making the unified data available for further analysis or machine learning purposes.

Create and configure AWS Glue notebook for lineage generation

Complete the following steps to create the AWS Glue notebook:

  1. On the AWS Glue console, choose Author using an interactive code notebook.
  2. Under Options, choose Start fresh and choose Create notebook.
  3. In the notebook, use the following code to generate lineage.

    In the following code, we add the required Spark configuration to generate lineage and then read CSV data from Amazon S3 and write in Parquet format to the Data Catalog table. The Spark configuration includes the following parameters:

    • spark.extraListeners=io.openlineage.spark.agent.OpenLineageSparkListener – Registers the OpenLineage listener to capture Spark job execution events and metadata for lineage tracking
    • spark.openlineage.transport.type=amazon_datazone_api – Specifies Amazon DataZone as the destination service where the lineage data will be sent and stored
    • spark.openlineage.transport.domainId=dzd_xxxxxxx – Defines the unique identifier of your Amazon DataZone domain where the lineage data will be associated
    • spark.glue.accountId={account_id} – Specifies the AWS account ID where the AWS Glue job is running for proper resource identification and access
    • spark.openlineage.facets.custom_environment_variables – Lists the specific environment variables to capture in the lineage data for context about the AWS and AWS Glue environment
    • spark.glue.JOB_NAME=lineagenotebook – Sets a unique identifier name for the AWS Glue job that will appear in lineage tracking and logs

    See the following code:

    %%configure —name project.spark -f
    {
    "—conf":"spark.extraListeners=io.openlineage.spark.agent.OpenLineageSparkListener \
    --conf spark.openlineage.transport.type=amazon_datazone_api \
    --conf spark.openlineage.transport.domainId=dzd_xxxxxxxx \
    --conf spark.glue.accountId={account_id} \
    --conf spark.openlineage.facets.custom_environment_variables=[AWS_DEFAULT_REGION;GLUE_VERSION;GLUE_COMMAND_CRITERIA;GLUE_PYTHON_VERSION;] \
    --conf spark.glue.JOB_NAME=lineagenotebook"
    }
    
    from pyspark.sql import SparkSession
    from pyspark.sql import SparkSession, DataFrame
    from pyspark.sql.functions import *
    from pyspark.sql.types import *
    from pyspark import SparkContext
    from pyspark.sql import SparkSession
    import sys
    import logging
    
    
    spark = SparkSession.builder.appName("lineagegluenotebook").enableHiveSupport().getOrCreate()
    
    s3_paths = {
    'absent_data': 's3://datazone-{account_id}/csv/attendance.csv'
    }
    absent_df = spark.read.csv(s3_paths['absent_data'], header=True, inferSchema=True)
    
    absent_df.write.mode("overwrite").format("parquet").option("path", "s3://datazone-{account_id}/attendanceparquet2/").saveAsTable("gluedbname.tablename")

  4. After the notebook has executed successfully, navigate to the SageMaker Unified Studio domain.
  5. Choose Project and under Overview, choose Data Sources.
  6. Choose the Data Catalog source ({account_id}-AwsDataCatalog-glue_db_suffix-default-datasource).
  7. Choose Run to create the asset attendance_with_empnote in SageMaker Catalog.
  8. Navigate to Assets, choose the attendance_with_empnote asset, and navigate to the LINEAGE section.

The following lineage diagram shows an AWS Glue job that reads data from the employee absence records stored in Amazon S3. The AWS Glue job transform CSV data into Parquet format, then creates a table in the Data Catalog and registers it as an asset in SageMaker Catalog.

Capture lineage from Amazon Redshift

To demonstrate the lineage, we are creating an employee table and an attendance table and join both datasets. Finally, we create a new table called employeewithabsent in Amazon Redshift. Complete the following steps to create and configure lineage for Amazon Redshift tables:

  1. In SageMaker Unified Studio, open your domain.
  2. Under Compute, choose Data warehouse.
  3. Open project.redshift and copy the endpoint name (redshift-serverless-workgroup-xxxxxxx).
  4. On the Amazon Redshift console, open the Query Editor v2, and connect to the Redshift Serverless workgroup with a secret. Use the AWS Secrets Manager option and choose the secret redshift-serverless-namespace-xxxxxxxx.
  5. Use the following code to create tables in Amazon Redshift and load data from Amazon S3 using the COPY command. Make sure the IAM role has GetObject permission on the S3 files attendance.csv and employees.csv.

    Create Redshift table absent

    CREATE TABLE public.absent (
        employeeid character varying(65535),
        date date,
        shiftstart timestamp without time zone ,
        shiftend timestamp without time zone,
        absent boolean,
        overtimehours integer
    );

    Load data into absent table.

    COPY absent
    FROM 's3://datazone-{account_id}/csv/attendance.csv' 
    IAM_ROLE 'arn:aws:iam::accountid:role/RedshiftAdmin'
    csv
    IGNOREHEADER 1;

    Create Redshift table employee

    CREATE TABLE public.employee (
        employeeid character varying(65535),
        name character varying(65535),
        department character varying(65535),
        role character varying(65535),
        hiredate date,
        salary double precision,
        performancerating integer,
        shift character varying(65535),
        location character varying(65535)
    );

    Load data into employee table.

    COPY employee
    FROM 's3://datazone-{account_id}/csv/employees.csv' 
    IAM_ROLE 'arn:aws:iam::account-id:role/RedshiftAdmin'
    csv
    IGNOREHEADER 1;

  6. After the tables are created and the data is loaded, perform the join between the tables and create a new table with a CTAS query:
    CREATE TABLE public.employeewithabsent AS
    SELECT 
      e.*,
      a.absent,
      a.overtimehours
    FROM public.employee e
    INNER JOIN public.absent a
    ON e.EmployeeID = a.EmployeeID;

  7. Navigate to the SageMaker Unified Studio domain.
  8. Choose Project and under Overview, choose Data Sources.
  9. Select the Amazon Redshift source (RedshiftServerless-default-redshift-datasource).
  10. On the Actions dropdown menu, choose Edit.
  11. Under Connection, Enable Import data lineage.
  12. In the Data Selection section, under Table Selection Criteria, provide a table name or use * to generate lineage.
  13. Update the data source and choose Run to create an asset called employeewithabsent in SageMaker Catalog.
  14. Navigate to Assets, choose the employeewithabsent asset, and navigate to the LINEAGE section.

The following lineage diagram shows joining two redshift tables and creating a new redshift table and registers it as an asset in SageMaker Catalog.

Capture lineage from EMR Serverless job

To demonstrate the lineage, we read employee data from an RDS for MySQL table and an attendance dataset from Amazon Redshift, and join both datasets. Finally, we write the data to Amazon S3 and create the attendance_with_employee table in the Data Catalog. Complete the following steps:

  1. On the Amazon EMR console, choose EMR Serverless in the navigation pane.
  2. To create or manage EMR Serverless applications, you need the EMR Studio UI.
    1. If you already have an EMR Studio in the Region where you want to create an application, choose Manage applications to navigate to your EMR Studio, or select the EMR Studio that you want to use.
    2. If you don’t have an EMR Studio in the Region where you want to create an application, choose Get started and then choose Create and launch Studio. EMR Serverless creates an EMR Studio for you so you can create and manage applications.
  3. In the Create studio UI that opens in a new tab, enter the name, type, and release version for your application.
  4. Choose Create application.
  5. Create an EMR Spark serverless application with the following configuration:
    1. For Type, choose Spark.
    2. For Release version, choose emr-7.8.0.
    3. For Architecture, choose x86_64.
    4. For Application setup options, select Use custom settings.
    5. For Interactive endpoint, enable the endpoint for EMR Studio.
    6. For Application configuration, use the following configuration:
      [{
          "Classification": "iceberg-defaults",
          "Properties": {
              "iceberg.enabled": "true"
          }
      }]

  6. Choose Create and Start application.
  7. After application has started, submit the Spark application to generate lineage events. Copy the following script and upload it to the S3 bucket (s3://datazone-{account_id}/script/). Upload the MySQL-connector-java JAR file to the S3 bucket (s3://datazone-{account_id}/jars/) to read the data from MySQL.
    from pyspark.sql import SparkSession
    from pyspark.sql import SparkSession, DataFrame
    from pyspark.sql.functions import *
    from pyspark.sql.types import *
    from pyspark import SparkContext
    from pyspark.sql import SparkSession
    import sys
    import logging
    
    
    spark = SparkSession.builder.appName("lineageglue").enableHiveSupport().getOrCreate()
    
    employee_df = spark.read.format("jdbc").option("driver","com.MySQL.cj.jdbc.Driver").option("url", "jdbc:MySQL://dbhostname:3306/databasename").option("dbtable", "employee").option("user", "admin").option("password", "xxxxxxx").load()
    
    absent_df = spark.read.format("jdbc").option("url", "jdbc:redshift://redshiftserverlessendpoint:5439/dev").option("dbtable", "public.absent").option("user", "admin").option("password", "xxxxxxxxxx").load()
    
    joined_df = employee_df.join(absent_df, on="EmployeeID", how="inner")
    
    joined_df.write.mode("overwrite").format("parquet").option("path", "s3://datazone-{account_id}/emrparquetnew/").saveAsTable("gluedname.tablename")

  8. After you upload the script, use the following command to submit the Spark application. Change the following parameters according to your environment details:
    1. application-id: Provide the Spark application ID you generated.
    2. execution-role-arn: Provide the EMR execution role.
    3. entryPoint: Provide the Spark script S3 path.
    4. domainID: Provide the domain ID (from the CloudFormation template output for DataZoneDomainid: dzd_xxxxxxxx).
    5. accountID: Provide your AWS account ID.
      aws emr-serverless start-job-run --application-id 00frv81tsqe0ok0l --execution-role-arn arn:aws:iam::{account_id}:role/service-role/AmazonEMR-ExecutionRole-1717662744320 --name "Spark-Lineage" --job-driver '{
              "sparkSubmit": {
                  "entryPoint": "s3://datazone-{account_id}/script/emrspark2.py",
                  "sparkSubmitParameters": "--conf spark.executor.cores=1 --conf spark.executor.memory=4g --conf spark.driver.cores=1 --conf spark.driver.memory=4g --conf spark.executor.instances=2 --conf spark.hadoop.hive.metastore.client.factory.class=com.amazonaws.glue.catalog.metastore.AWSGlueDataCatalogHiveClientFactory --conf spark.jars=/usr/share/aws/datazone-openlineage-spark/lib/DataZoneOpenLineageSpark-1.0.jar,s3://datazone-{account_id}/jars/MySQL-connector-java-8.0.20.jar --conf spark.extraListeners=io.openlineage.spark.agent.OpenLineageSparkListener --conf spark.openlineage.transport.type=amazon_datazone_api --conf spark.openlineage.transport.domainId=dzd_xxxxxxxx --conf spark.glue.accountId={account_id}"
              }
          }'

  9. After the job has executed successfully, navigate to the SageMaker Unified Studio domain.
  10. Choose Project and under Overview, choose Data Sources.
  11. Select the Data Catalog source ({account_id}-AwsDataCatalog-glue_db_xxxxxxxxxx-default-datasource).
  12. On the Actions dropdown menu, choose Edit.
  13. Under Connection, enable Import data lineage.
  14. In the Data Selection section, under Table Selection Criteria, provide a table name or use * to generate lineage.
  15. Update the data source and choose Run to create an asset called attendancewithempnew in SageMaker Catalog.
  16. Navigate to Assets, choose the attendancewithempnew asset, and navigate to the LINEAGE section.

The following lineage diagram shows an AWS Glue job that integrates employee information stored in Amazon RDS for MySQL and employee absence records stored in Amazon Redshift. The AWS Glue job combines these datasets through a join operation, then creates a table in the Data Catalog and registers it as an asset in SageMaker Catalog.

Clean up

To clean up your resources, complete the following steps:

  1. On the AWS Glue console, delete the AWS Glue job.
  2. On the Amazon EMR console, delete the EMR Serverless Spark application and EMR Studio.
  3. On the AWS CloudFormation console, delete the CloudFormation stack vpc-analytics-lineage-sus.

Conclusion

In this post, we showed how data lineage in SageMaker Catalog helps you track and understand the complete lifecycle of your data across various AWS analytics services. This comprehensive tracking system provides visibility into how data flows through different processing stages, transformations, and analytical workflows, making it an essential tool for data governance, compliance, and operational efficiency.

Try out these lineage visualization methods for your own use cases, and share your questions and feedback in the comments section.


About the Authors

Shubham Purwar

Shubham Purwar

Shubham is an AWS Analytics Specialist Solution Architect. He helps organizations unlock the full potential of their data by designing and implementing scalable, secure, and high-performance analytics solutions on the AWS platform. With deep expertise in AWS analytics services, he collaborates with customers to uncover their distinct business requirements and create customized solutions that deliver actionable insights and drive business growth. In his free time, Shubham loves to spend time with his family and travel around the world.

Nitin Kumar

Nitin Kumar

Nitin is a Cloud Engineer (ETL) at Amazon Web Services, specialized in AWS Glue. With a decade of experience, he excels in aiding customers with their big data workloads, focusing on data processing and analytics. He is committed to helping customers overcome ETL challenges and develop scalable data processing and analytics pipelines on AWS. In his free time, he likes to watch movies and spend time with his family.

Prashanthi Chinthala

Prashanthi Chinthala

Prashanthi is a Cloud Engineer (DIST) at AWS. She helps customers overcome EMR challenges and develop scalable data processing and analytics pipelines on AWS.

Seamlessly Integrate Data on Google BigQuery and ClickHouse Cloud with AWS Glue

Post Syndicated from Ray Wang original https://aws.amazon.com/blogs/big-data/seamlessly-integrate-data-on-google-bigquery-and-clickhouse-cloud-with-aws-glue/

Migrating from Google Cloud’s BigQuery to ClickHouse Cloud on AWS allows businesses to leverage the speed and efficiency of ClickHouse for real-time analytics while benefiting from AWS’s scalable and secure environment. This article provides a comprehensive guide to executing a direct data migration using AWS Glue ETL, highlighting the advantages and best practices for a seamless transition.

AWS Glue ETL enables organizations to discover, prepare, and integrate data at scale without the burden of managing infrastructure. With its built-in connectivity, Glue can seamlessly read data from Google Cloud’s BigQuery and write it to ClickHouse Cloud on AWS, removing the need for custom connectors or complex integration scripts. Beyond connectivity, Glue also provides advanced capabilities such as a visual ETL authoring interface, automated job scheduling, and serverless scaling, allowing teams to design, monitor, and manage their pipelines more efficiently. Together, these features simplify data integration, reduce latency, and deliver significant cost savings, enabling faster and more reliable migrations.

Prerequisites

Before using AWS Glue to integrate data into ClickHouse Cloud, you must first set up the ClickHouse environment on AWS. This includes creating and configuring your ClickHouse Cloud on AWS, making sure network access and security groups are properly defined, and verifying that the cluster endpoint is accessible. Once the ClickHouse environment is ready, you can leverage the AWS Glue built-in connector to seamlessly write data into ClickHouse Cloud from sources such as Google Cloud BigQuery. You can follow the next section to complete the setup.

  1. Set up ClickHouse Cloud on AWS
    1. Follow the ClickHouse official website to set up environment (remember to allow remote access in the config file if using Clickhouse OSS)
      https://clickhouse.com/docs/get-started/quick-start
  2. Subscribe the ClickHouse Glue marketplace connector
    1. Open Glue Connectors and choose Go to AWS Marketplace
    2. On the list of AWS Glue marketplace connectors, enter ClickHouse in the search bar. Then choose ClickHouse Connector for AWS Glue
    3. Choose View purchase options on the right top of the view
    4. Review Terms and Conditions and choose Accept Terms
    5. Choose Continue to Configuration once it’s enabled
    6. On Follow the vendor’s instructions part in the connector instructions as below, choose the connector enabling link at step 3

Configure AWS Glue ETL Job for ClickHouse Integration

AWS Glue enables direct migration by connecting with ClickHouse Cloud on AWS through built-in connectors, allowing for seamless ETL operations. Within the Glue console, users can configure jobs to read data from S3 and write it directly to ClickHouse Cloud. Using AWS Glue Data Catalog, data in S3 can be indexed for efficient processing, while Glue’s PySpark support allows for complex data transformations, including data type conversions, to support compatibility with ClickHouse’s schema.

  1. Open AWS Glue in the AWS Management Console
    1. Navigate to Data Catalog and Connections
    2. Create a new connection
  2. Configure BigQuery Connection in Glue
    1. Prepare a Google Cloud BigQuery Environment
    2. Create and Store Google Cloud Service Account Key (JSON format) in AWS Secret Manager, you can find the details in BigQuery connections.
    3. The JSON Format content example is as following:
      {
        "type": "service_account",
        "project_id": "h*********g0",
        "private_key_id": "cc***************81",
        "private_key": "-----BEGIN PRIVATE KEY-----\nMI***zEc=\n-----END PRIVATE KEY-----\n",
        "client_email": "clickhouse-sa@h*********g0.iam.gserviceaccount.com",
        "client_id": "1*********8",
        "auth_uri": "https://accounts.google.com/o/oauth2/auth",
        "token_uri": "https://oauth2.googleapis.com/token",
        "auth_provider_x509_cert_url": "https://www.googleapis.com/oauth2/v1/certs",
        "client_x509_cert_url": "https://www.googleapis.com/robot/v1/metadata/x509/clickhouse-sa%40h*********g0.iam.gserviceaccount.com",
        "universe_domain": "googleapis.com"
      }

      • type: service_account.
      • project_id: The ID of the GCP project.
      • private_key_id: A unique ID for the private key within the file.
      • private_key: The actual private key.
      • client_email: The email address of the service account.
      • client_id: A unique client ID associated with the service account.
      • auth_uri, token_uri, auth_provider_x509_cert_url
      • client_x509_cert_url: URLs for authentication and token exchange with Google’s identity and access management systems.
      • universe_domain: The domain name of GCP, googleapis.com
    4. Create Google BigQuery Connection in AWS Glue
    5. Grant the IAM role associated with your AWS Glue job permission for S3, Secret Manager, Glue services, and AmazonEC2ContainerRegistryReadOnly for accessing connectors purchased from AWS Marketplace (reference doc)
  3. Create ClickHouse connection in AWS Glue
    1. Enter clickhouse-connection as its connection name
    2. Choose Create connection and activate connector
  4. Create a Glue job
    1. On the Connectors view as below, select clickhouse-connection and choose Create job
    2. Enter bq_to_clickhouse as its job name and configure gc_connector_role as its IAM Role
    3. Configure BigQuery connection and clickhouse-connection to the Connection property
    4. Choose the Script tab and Edit script. Then choose Confirm on the Edit script popup view.
    5. Copy and paste the following code onto the script editor which can be referred from clickhouse official doc
    6. The source code is as following:
      import sys
      from pyspark.sql import SparkSession
      from awsglue.context import GlueContext
      from awsglue.job import Job
      from awsglue.utils import getResolvedOptions
      
      args = getResolvedOptions(sys.argv, ['JOB_NAME'])
      spark = SparkSession.builder.getOrCreate()
      glueContext = GlueContext(spark.sparkContext)
      job = Job(glueContext)
      job.init(args['JOB_NAME'], args)
      
      connection_options = {
          "connectionName": "Bigquery connection",
          "parentProject": "YOUR_GCP_PROJECT_ID",
          "query": "SELECT * FROM `YOUR_GCP_PROJECT_ID.bq_test_dataset.bq_test_table`",
          "viewsEnabled": "true",
          "materializationDataset": "bq_test_dataset"
      }
      jdbc_url = " jdbc:clickhouse://YOUR_CLICKHOUSE_CONNECTION.us-east-1.aws.clickhouse.cloud:8443/clickhouse_database?ssl=true "
      username = "default"
      password = "YOUR_PASSWORD"
      query = "select * from clickhouse_database.clickhouse_test_table"
      # Add this before writing to test connection
      try:
          # Read from BigQuery with Glue Connection
          print("Reading data from BigQuery...")
          GoogleBigQuery_node1742453400261 = glueContext.create_dynamic_frame.from_options(
              connection_type="bigquery",
              connection_options=connection_options,
              transformation_ctx="GoogleBigQuery_node1742453400261"
          )
          # Convert to DataFrame
          bq_df = GoogleBigQuery_node1742453400261.toDF()
          print("Show data from BigQuery:")
          bq_df.show()
          
          # Write BigQuery Data to Clickhouse with JDBC
          bq_df.write \
          .format("jdbc") \
          .option("driver", 'com.clickhouse.jdbc.ClickHouseDriver') \
          .option("url", jdbc_url) \
          .option("user", username) \
          .option("password", password) \
          .option("dbtable", "clickhouse_test_table") \
          .mode("append") \
          .save()
          
          print("Write BigQuery Data to ClickHouse successfully")
          
          # Read from Clickhouse with JDBC
          reaf_df = (spark.read.format("jdbc")
          .option("driver", 'com.clickhouse.jdbc.ClickHouseDriver')
          .option("url", jdbc_url)
          .option("user", username)
          .option("password", password)
          .option("query", query)
          .option("ssl", "true")
          .load())
          
          print("Show Data from ClickHouse:")
          reaf_df.show()
          
      except Exception as e:
          print(f"ClickHouse connection test failed: {str(e)}")
          raise e
      finally:
          job.commit()

    7. Choose Save and Run on the right top of the current view

Testing and Validation

Testing is crucial to verify data accuracy and performance in the new environment. After the migration completes, run data integrity checks to confirm record counts and data quality in ClickHouse Cloud. Schema validation is essential, as each data field must align correctly with ClickHouse’s format. Running performance benchmarks, such as sample queries, will help verify that ClickHouse’s setup delivers the desired speed and efficiency gains.

  1. The Schema and Data in source BigQuery and destination Clickhouse

  2. AWS Glue output logs

Clean Up

After completing the migration, it’s important to clean up unused resources—such as BigQuery for sample data import and database resources in ClickHouse Cloud—to avoid unnecessary costs. Regarding IAM permissions, adhering to the principle of least privilege is advisable. This involves granting users and roles only the permissions necessary for their tasks and removing unnecessary permissions when they are no longer required. This approach enhances security by minimizing potential threat surfaces. Additionally, reviewing AWS Glue job costs and configurations can help identify optimization opportunities for future migrations. Monitoring overall costs and analyzing usage can reveal areas where code or configuration improvements may lead to cost savings.

Conclusion

AWS Glue ETL offers a robust and user-friendly solution for migrating data from BigQuery to ClickHouse Cloud on AWS. By utilizing Glue’s serverless architecture, organizations can perform data migrations that are efficient, secure, and cost-effective. The direct integration with ClickHouse streamlines data transfer, supporting high performance and flexibility. This migration approach is particularly well-suited for companies looking to enhance their real-time analytics capabilities on AWS.


About the Authors

Ray Wang

Ray Wang

Ray is a Senior Solutions Architect at AWS. With 12+ years of experience in the IT industry, Ray is dedicated to building modern solutions on the cloud, especially in NoSQL, big data, machine learning, and Generative AI. As a hungry go-getter, he passed all 12 AWS certificates to make his technical field not only deep but wide. He loves to read and watch sci-fi movies in his spare time.

Robert Chung

Robert Chung

Robert is a Solutions Architect at AWS with expertise across Infrastructure, Data, AI, and Modernization technologies. He has supported numerous financial services customers in driving cloud-native transformation, advancing data analytics, and accelerating mainframe modernization. His experience also extends to modern AI-DLC practices, enabling enterprises to innovate faster. With this background, Robert is well-equipped to address complex enterprise challenges and deliver impactful solutions.

Tomohiro Tanaka

Tomohiro Tanaka

Tomohiro is a Senior Cloud Support Engineer at Amazon Web Services (AWS). He’s passionate about helping customers use Apache Iceberg for their data lakes on AWS. In his free time, he enjoys a coffee break with his colleagues and making coffee at home.

Stanley Chukwuemeke

Stanley Chukwuemeke

Stanley is a Senior Partner Solutions Architect at AWS. He works with AWS technology partners to grow their business by creating joint go-to-market solutions using AWS data, analytics and AI services. He’s worked with data most of his career and passionate about database modernization and cloud adoption strategy to help drive enterprise modernization initiatives across industries.

Break down data silos and seamlessly query Iceberg tables in Amazon SageMaker from Snowflake

Post Syndicated from Nidhi Gupta original https://aws.amazon.com/blogs/big-data/break-down-data-silos-and-seamlessly-query-iceberg-tables-in-amazon-sagemaker-from-snowflake/

Organizations often struggle to unify their data ecosystems across multiple platforms and services. The connectivity between Amazon SageMaker and Snowflake’s AI Data Cloud offers a powerful solution to this challenge, so businesses can take advantage of the strengths of both environments while maintaining a cohesive data strategy.

In this post, we demonstrate how you can break down data silos and enhance your analytical capabilities by querying Apache Iceberg tables in the lakehouse architecture of SageMaker directly from Snowflake. With this capability, you can access and analyze data stored in Amazon Simple Storage Service (Amazon S3) through AWS Glue Data Catalog using an AWS Glue Iceberg REST endpoint, all secured by AWS Lake Formation, without the need for complex extract, transform, and load (ETL) processes or data duplication. You can also automate table discovery and refresh using Snowflake catalog-linked databases for Iceberg. In the following sections, we show how to set up this integration so Snowflake users can seamlessly query and analyze data stored in AWS, thereby improving data accessibility, reducing redundancy, and enabling more comprehensive analytics across your entire data ecosystem.

Business use cases and key benefits

The capability to query Iceberg tables in SageMaker from Snowflake delivers significant value across multiple industries:

  • Financial services – Enhance fraud detection through unified analysis of transaction data and customer behavior patterns
  • Healthcare – Improve patient outcomes through integrated access to clinical, claims, and research data
  • Retail – Increase customer retention rates by connecting sales, inventory, and customer behavior data for personalized experiences
  • Manufacturing – Boost production efficiency through unified sensor and operational data analytics
  • Telecommunications – Reduce customer churn with comprehensive analysis of network performance and customer usage data

Key benefits of this capability include:

  • Accelerated decision-making – Reduce time to insight through integrated data access across platforms
  • Cost optimization – Accelerate time to insight by querying data directly in storage without the need for ingestion
  • Improved data fidelity – Reduce data inconsistencies by establishing a single source of truth
  • Enhanced collaboration – Increase cross-functional productivity through simplified data sharing between data scientists and analysts

By using the lakehouse architecture of SageMaker with Snowflake’s serverless and zero-tuning computational power, you can break down data silos, enabling comprehensive analytics and democratizing data access. This integration supports a modern data architecture that prioritizes flexibility, security, and analytical performance, ultimately driving faster, more informed decision-making across the enterprise.

Solution overview

The following diagram shows the architecture for catalog integration between Snowflake and Iceberg tables in the lakehouse.

Catalog integration to query Iceberg tables in S3 bucket using Iceberg REST Catalog (IRC) with credential vending

The workflow consists of the following components:

  • Data storage and management:
    • Amazon S3 serves as the primary storage layer, hosting the Iceberg table data
    • The Data Catalog maintains the metadata for these tables
    • Lake Formation provides credential vending
  • Authentication flow:
    • Snowflake initiates queries using a catalog integration configuration
    • Lake Formation vends temporary credentials through AWS Security Token Service (AWS STS)
    • These credentials are automatically refreshed based on the configured refresh interval
  • Query flow:
    • Snowflake users submit queries against the mounted Iceberg tables
    • The AWS Glue Iceberg REST endpoint processes these requests
    • Query execution uses Snowflake’s compute resources while reading directly from Amazon S3
    • Results are returned to Snowflake users while maintaining all security controls

There are four patterns to query Iceberg tables in SageMaker from Snowflake:

  • Iceberg tables in an S3 bucket using an AWS Glue Iceberg REST endpoint and Snowflake Iceberg REST catalog integration, with credential vending from Lake Formation
  • Iceberg tables in an S3 bucket using an AWS Glue Iceberg REST endpoint and Snowflake Iceberg REST catalog integration, using Snowflake external volumes to Amazon S3 data storage
  • Iceberg tables in an S3 bucket using AWS Glue API catalog integration, also using Snowflake external volumes to Amazon S3
  • Amazon S3 Tables using Iceberg REST catalog integration with credential vending from Lake Formation

In this post, we implement the first of these four access patterns using catalog integration for the AWS Glue Iceberg REST endpoint with Signature Version 4 (SigV4) authentication in Snowflake.

Prerequisites

You must have the following prerequisites:

The solution takes approximately 30–45 minutes to set up. Cost varies based on data volume and query frequency. Use the AWS Pricing Calculator for specific estimates.

Create an IAM role for Snowflake

To create an IAM role for Snowflake, you first create a policy for the role:

  1. On the IAM console, choose Policies in the navigation pane.
  2. Choose Create policy.
  3. Choose the JSON editor and enter the following policy (provide your AWS Region and account ID), then choose Next.
{
     "Version": "2012-10-17",
     "Statement": [
         {
             "Sid": "AllowGlueCatalogTableAccess",
             "Effect": "Allow",
             "Action": [
                 "glue:GetCatalog",
                 "glue:GetCatalogs",
                 "glue:GetPartitions",
                 "glue:GetPartition",
                 "glue:GetDatabase",
                 "glue:GetDatabases",
                 "glue:GetTable",
                 "glue:GetTables",
                 "glue:UpdateTable"
             ],
             "Resource": [
                 "arn:aws:glue:<region>:<account-id>:catalog",
                 "arn:aws:glue:<region>:<account-id>:database/iceberg_db",
                 "arn:aws:glue:<region>:<account-id>:table/iceberg_db/*",
             ]
         },
         {
             "Effect": "Allow",
             "Action": [
                 "lakeformation:GetDataAccess"
             ],
             "Resource": "*"
         }
     ]
 }
  1. Enter iceberg-table-access as the policy name.
  2. Choose Create policy.

Now you can create the role and attach the policy you created.

  1. Choose Roles in the navigation pane.
  2. Choose Create role.
  3. Choose AWS account.
  4. Under Options, select Require External Id and enter an external ID of your choice.
  5. Choose Next.
  6. Choose the policy you created (iceberg-table-access policy).
  7. Enter snowflake_access_role as the role name.
  8. Choose Create role.

Configure Lake Formation access controls

To configure your Lake Formation access controls, first set up the application integration:

  1. Sign in to the Lake Formation console as a data lake administrator.
  2. Choose Administration in the navigation pane.
  3. Select Application integration settings.
  4. Enable Allow external engines to access data in Amazon S3 locations with full table access.
  5. Choose Save.

Now you can grant permissions to the IAM role.

  1. Choose Data permissions in the navigation pane.
  2. Choose Grant.
  3. Configure the following settings:
    1. For Principals, select IAM users and roles and choose snowflake_access_role.
    2. For Resources, select Named Data Catalog resources.
    3. For Catalog, choose your AWS account ID.
    4. For Database, choose iceberg_db.
    5. For Table, choose customer.
    6. For Permissions, select SUPER.
  4. Choose Grant.

SUPER access is required for mounting the Iceberg table in Amazon S3 as a Snowflake table.

Register the S3 data lake location

Complete the following steps to register the S3 data lake location:

  1. As data lake administrator on the Lake Formation console, choose Data lake locations in the navigation pane.
  2. Choose Register location.
  3. Configure the following:
    1. For S3 path, enter the S3 path to the bucket where you will store your data.
    2. For IAM role, choose LakeFormationLocationRegistrationRole.
    3. For Permission mode, choose Lake Formation.
  4. Choose Register location.

Set up the Iceberg REST integration in Snowflake

Complete the following steps to set up the Iceberg REST integration in Snowflake:

  1. Log in to Snowflake as an admin user.
  2. Execute the following SQL command (provide your Region, account ID, and external ID that you provided during IAM role creation):
CREATE OR REPLACE CATALOG INTEGRATION glue_irc_catalog_int
CATALOG_SOURCE = ICEBERG_REST
TABLE_FORMAT = ICEBERG
CATALOG_NAMESPACE = 'iceberg_db'
REST_CONFIG = (
    CATALOG_URI = 'https://glue.<region>.amazonaws.com/iceberg'
    CATALOG_API_TYPE = AWS_GLUE
    CATALOG_NAME = '<account-id>'
    ACCESS_DELEGATION_MODE = VENDED_CREDENTIALS
)
REST_AUTHENTICATION = (
    TYPE = SIGV4
    SIGV4_IAM_ROLE = 'arn:aws:iam::<account-id>:role/snowflake_access_role'
    SIGV4_SIGNING_REGION = '<region>'
    SIGV4_EXTERNAL_ID = '<external-id>'
)
REFRESH_INTERVAL_SECONDS = 120
ENABLED = TRUE;
  1. Execute the following SQL command and retrieve the value for API_AWS_IAM_USER_ARN:

DESCRIBE CATALOG INTEGRATION glue_irc_catalog_int;

  1. On the IAM console, update the trust relationship for snowflake_access_role with the value for API_AWS_IAM_USER_ARN:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "",
            "Effect": "Allow",
            "Principal": {
                "AWS": [
                   "<API_AWS_IAM_USER_ARN>"
                ]
            },
            "Action": "sts:AssumeRole",
            "Condition": {
                "StringEquals": {
                    "sts:ExternalId": [
                        "<external-id>"
                    ]
                }
            }
        }
    ]
}
  1. Verify the catalog integration:

SELECT SYSTEM$VERIFY_CATALOG_INTEGRATION('glue_irc_catalog_int');

  1. Mount the S3 table as a Snowflake table:
CREATE OR REPLACE ICEBERG TABLE s3iceberg_customer
 CATALOG = 'glue_irc_catalog_int'
 CATALOG_NAMESPACE = 'iceberg_db'
 CATALOG_TABLE_NAME = 'customer'
 AUTO_REFRESH = TRUE;

Query the Iceberg table from Snowflake

To test the configuration, log in to Snowflake as an admin user and run the following sample query:SELECT * FROM s3iceberg_customer LIMIT 10;

Clean up

To clean up your resources, complete the following steps:

  1. Delete the database and table in AWS Glue.
  2. Drop the Iceberg table, catalog integration, and database in Snowflake:
DROP ICEBERG TABLE iceberg_customer;
DROP CATALOG INTEGRATION glue_irc_catalog_int;

Make sure all resources are properly cleaned up to avoid unexpected charges.

Conclusion

In this post, we demonstrated how to establish a secure and efficient connection between your Snowflake environment and SageMaker to query Iceberg tables in Amazon S3. This capability can help your organization maintain a single source of truth while also letting teams use their preferred analytics tools, ultimately breaking down data silos and enhancing collaborative analysis capabilities.

To further explore and implement this solution in your environment, consider the following resources:

These resources can help you to implement and optimize this integration pattern for your specific use case. As you begin this journey, remember to start small, validate your architecture with test data, and gradually scale your implementation based on your organization’s needs.


About the authors

Nidhi Gupta

Nidhi Gupta

Nidhi is a Senior Partner Solutions Architect at AWS, specializing in data and analytics. She helps customers and partners build and optimize Snowflake workloads on AWS. Nidhi has extensive experience leading production releases and deployments, with focus on Data, AI, ML, generative AI, and Advanced Analytics.

Andries Engelbrecht

Andries Engelbrecht

Andries is a Principal Partner Solutions Engineer at Snowflake working with AWS. He supports product and service integrations, as well the development of joint solutions with AWS. Andries has over 25 years of experience in the field of data and analytics.

Accelerate AWS Glue Zero-ETL data ingestion using Salesforce Bulk API

Post Syndicated from Shashank Sharma original https://aws.amazon.com/blogs/big-data/accelerate-aws-glue-zero-etl-data-ingestion-using-salesforce-bulk-api/

Efficiently integrating and analyzing Salesforce data is essential in today’s business environment. AWS Glue Zero ETL (extract, transform, and load) now supports Salesforce Bulk API, delivering substantial performance gains compared to Salesforce REST API for large-scale data integration for targets such as Amazon SageMaker lakehouse and Amazon Redshift. You can use this enhancement to process millions of Salesforce records in minutes while efficiently handling wide-column entities with hundreds of fields. In this blog post, we show you how to use Zero-ETL powered by AWS Glue with Salesforce Bulk API to accelerate your data integration processes.

Zero-ETL represents a modern approach to data integration that eliminates the need for traditional ETL processes by establishing direct connections between data sources and destinations. Rather than explicitly extracting data, transforming it, and loading it in separate steps, Zero-ETL handles these operations in the background. Zero-ETL enables direct integration with software as a service (SaaS) applications like Salesforce, automatically synchronizing data while maintaining consistency and eliminating the complexity of manual ETL pipeline development. This approach reduces development time, maintenance overhead, and the potential for errors in data movement processes.

Solution overview

Traditionally, Zero-ETL used Salesforce REST API for data ingestion. While the REST API provides a straightforward way to interact with Salesforce data, it comes with certain limitations, especially when dealing with large datasets. These include request limits, data volume constraints, performance overhead, and concurrency limitations. As of August 2025, depending on the Salesforce edition and license type, you might be limited to between 15,000 and 100,000 API calls per 24-hour period. When retrieving large volumes of data, multiple API calls are required, leading to inefficiency and extended processing times.

To address these limitations and enhance performance, AWS Glue Zero-ETL now supports Salesforce Bulk API. The Bulk API is designed for processing large datasets, offering several advantages over the REST API. It uses asynchronous processing, so you can process much larger data volumes without timing out. Data is processed in batches, which can be parallelized for faster processing. As of August 2025, the Bulk API also has more generous limits; up to 150,000,000 API calls, which is 15,000 batches, per 24-hour period, with each batch containing up to 10,000 records. The following diagram shows a Salesforce Zero-ETL architecture ingesting data through Salesforce Bulk and REST APIs and writing to Amazon SageMaker Lakehouse (in Amazon Simple Storage Service (Amazon S3) or Apache Iceberg) or Amazon Redshift.

AWS Glue Zero-ETL architecture highlighting data flow, API processing, and analytics capabilities with performance metrics

The diagram illustrates the Zero-ETL data flow from Salesforce to AWS analytics services. Salesforce data is ingested using smart API processing, which intelligently selects between Bulk API for standard fields and REST API for compound fields. This approach is necessary because, as of now, the Salesforce Bulk API does not support compound fields (such as Address). Therefore, you must use the REST API in such cases for comprehensive data extraction. The solution supports Salesforce wide-column entities containing up to 800 fields, enabling comprehensive data integration. The processed data is then staged in an S3 bucket owned by the service team before being made available in the AWS Glue Data Catalog or Amazon Redshift, ready for analytics and machine learning applications.

AWS Glue Zero-ETL now uses the Salesforce Bulk API by default for most data integration scenarios, delivering superior performance and scalability. This approach optimizes data extraction for most use cases, particularly when dealing with large datasets. However, the solution automatically switches to the REST API when handling compound fields. Compound fields, such as addresses (which include street, city, state, postal code, and country), are automatically processed using the REST API.This intelligent API selection provides efficient processing while maintaining the performance benefits of the Bulk API for standard data extraction. This hybrid approach provides the best of both worlds: the scalability and throughput of the Bulk API for most operations, with the specialized handling capabilities of the REST API where it makes the most sense. The system handles this switch automatically, so you don’t need to worry about which API to use for different scenarios.

Performance details

After implementing Salesforce Bulk API support in AWS Glue Zero-ETL, you can see significant performance improvements that scale dramatically with data volume. To test performance benefits, we created a custom object in our Salesforce account and populated it with 10 million records. We then established a Zero-ETL integration between Salesforce and AWS Glue databases to measure data transfer performance. The most impressive gains are evident with large-scale operations: processing 10 million records now completes in 6 minutes and 20 seconds compared to 28 minutes and 53 seconds with the REST API—representing a 4.6-fold improvement in processing time in our controlled testing environment, as shown in the following figure. Performance improvements can vary depending on factors such as data volume, field complexity, network conditions, and computational resources.

Graph demonstrating Bulk API's 4.6x performance advantage over REST API when processing 10M records

Multi-entity processing scenarios, where four different Salesforce objects are processed simultaneously, demonstrate the solution’s scalability. Even with this concurrent load, 1 million records across multiple entities complete processing in under 3 minutes, showcasing the Bulk API’s superior handling of real-world data integration scenarios, as shown in the following figure.

Multi-entity comparison graph demonstrating Bulk API's 4.6x performance advantage over REST when processing 4 objects at 10M scale

This performance pattern demonstrates that the Bulk API’s asynchronous, batch-oriented architecture delivers exceptional results when handling the large-scale data volumes that enterprises typically encounter in production Salesforce integrations. The performance advantage scales directly with data volume, making it particularly valuable for organizations processing millions of records in their daily operations. As dataset size increases, the efficiency gains become increasingly pronounced, establishing the Bulk API as the optimal choice for enterprise-scale data processing requirements.Beyond the impressive performance gains with large datasets, our recent enhancements have also unlocked another critical capability: efficient processing of wide-column entities. Our performance benchmarks demonstrate this capability in action, with custom objects containing up to 800 columns and 226 KB record sizes processing in just 2 minutes and 11 seconds, while entities with 500 columns and 140 KB records complete in 2 minutes and 3 seconds, and 100-column entities with 28 KB records process in 1 minute and 56 seconds (shown in the following figure). This remarkable consistency across varying column counts and record sizes demonstrates that Zero-ETL from SaaS applications maintains excellent performance while efficiently ingesting and processing these wide-column entities, which means that you can use your complete Salesforce datasets for analytics and machine learning initiatives.

Wide column processing graph demonstrating scalable integration times from 01:56 to 02:11 minutes across increasing data volumes

Impact

The performance improvements, demonstrated by AWS Glue Zero-ETL with Salesforce Bulk API support, offer tangible benefits for businesses managing large volumes of Salesforce data. As mentioned earlier, our controlled testing, demonstrated a 4.6-fold improvement over the REST API when processing 10 million records. With these results, you can significantly reduce your data integration time windows. This faster processing allows for more frequent data updates, potentially enabling you to work with fresher data for your analytics and reporting needs. Additionally, the efficient handling of wide-column entities, such as processing custom objects with up to 800 columns in just over 2 minutes, means that you can more readily use your complete Salesforce datasets without sacrificing performance.

Prerequisites

Before implementing this solution, you need to have the following in place:

  1. A Salesforce Enterprise, Unlimited, or Performance Edition account
  2. An AWS account with administrator access
  3. Create an AWS Glue database with a name such as zero_etl_bulk_demo_db and associate the S3 bucket zeroetl-etl-bulk-demo-bucket as a location of the database.
  4. Update AWS Glue Data Catalog settings using the following IAM policy for fine-grained access control of the data catalog for zero-ETL.
  5. Create an AWS Identity and Access Management (IAM) role named zero_etl_bulk_role. The IAM role will be used by Zero-ETL to access data from your Saleforce account
  6. Create the secret zero_etl_bulk_demo_secret in AWS Secrets Manager to store Salesforce credentials.

Build and verify the zero-ETL integration

This section covers the steps required to set up a Salesforce connection and using that connection to create a Zero-ETL integration.

Step 1: Set up a connector to your Salesforce instance to enable data access

  1. Open the AWS Management Console for AWS Glue.
  2. In the navigation pane, under Data catalog, choose Connections.
  3. Choose Create Connection.
  4. In the Create Connection pane, enter Salesforce in Data Sources.
  5. Choose Salesforce.
  6. Choose Next.

AWS Glue connection creation interface highlighting Salesforce data source options

  1. Enter the Salesforce URL Instance URL
  2. For IAM service role, select the zero_etl_bulk_demo_role (created as part of the prerequisites).
  3. For Authentication Type, select the authentication type that you’re using for Salesforce. In this example, we selected Authorization Code.
  4. For AWS Secret, select the secret zero_etl_bulk_demo_secret (created as part of the prerequisites).
  5. Choose Next.

AWS Glue data connection interface for configuring Salesforce integration with security credentials

  1. In the Connection Properties section, for Name, enter zero_etl_bulk_demo_conn.
  2. Choose Next.

Successfully configured AWS Glue Salesforce connector interface with connection details

Step 2: Set up Zero-ETL integration

  1. Open the AWS Glue console.
  2. In the navigation pane, under Data catalog, choose Zero-ETL integrations.
  3. Choose Create zero-ETL integration.
  4. In the Create integration pane, enter Salesforce in Data Sources.
  5. Choose Salesforce.
  6. Choose Next.

AWS Glue integration wizard displaying Salesforce data source options with four-step configuration process


  1. Select the connection name that you created in the previous step.
  2. Select the IAM role which you created in the previous step.
  3. For Salesforce object, select the objects you want to perform the ingestion managed by Zero-ETL integration. For this post, select Opportunity.

AWS Glue Zero-ETL configuration interface displaying Salesforce connection settings and opportunity objects selection

For Namespace or Database In this example, we use the zero_etl_bulk_demo_db (from the prerequisites).

  1. For Target IAM role, select the zero_etl_demo_role (from the prerequisites).
  2. Choose Next.

AWS Glue Zero-ETL target configuration interface with data warehouse selection

  1. In the Integration details section, for Name, enter zero-etl-bulk-demo-integration.
  2. Choose Next.

AWS Glue Zero-ETL configuration interface displaying AWS-managed KMS encryption, customizable replication timing, and integration naming

  1. Review the details and choose Create and launch integration.
  2. The newly created integration will show as Active in about a minute.

AWS Glue Zero-ETL integration dashboard displaying successful creation confirmation and monitoring status

Clean up

Note that following these steps will permanently delete the resources created in this post; back up any important data before proceeding.

  1. Delete the Zero-ETL integration zero-etl-bulk-demo-integration.
  2. Delete content from the S3 bucket zeroetl-etl-bulk-demo-bucket.
  3. Delete the Data Catalog database zero_etl_bulk_demo_db.
  4. Delete the Data Catalog connection zero_etl_bulk_demo_conn.
  5. Delete the Secrets Manager secret zero_etl_bulk_demo_secret.

Conclusion

The integration of Salesforce Bulk API support in AWS Glue Zero-ETL marks a significant advancement in our data integration capabilities. By addressing the limitations of the REST API, efficiently handling wide-column entities and compound fields, and implementing robust error handling, you can now use AWS Glue Zero-ETL to ingest larger volumes of Salesforce data more efficiently.This enhancement improves performance and opens up new possibilities for your organization to use their Salesforce data for analytics, machine learning, and other data-driven initiatives. As we continue to evolve AWS Glue Zero-ETL, we remain committed to providing cutting-edge solutions that empower our customers to make the most of their data integration processes.

Learn more


About the authors

Shashank Sharma

Shashank Sharma

Shashank is an Engineering Leader within AWS Glue delivering data integration and replication solutions for enterprise customers. He leads engineering for AWS Glue Zero-ETL and Amazon AppFlow.


Shashi Shekhar

Shashi Shekhar

Shashi is a Software Engineer within AWS Glue Zero-ETL, building scalable data pipeline solutions for enterprise workloads. He is passionate about distributed systems, performance engineering, and simplifying complex data integration processes.

Zero-ETL: How AWS is tackling data integration challenges

Post Syndicated from Nikki Rouda original https://aws.amazon.com/blogs/big-data/zero-etl-how-aws-is-tackling-data-integration-challenges/

In this blog post, we show you how Amazon Web Services (AWS) is simplifying data integration with zero-ETL while realizing performance benefits and cost optimizations. As organizations gather data for analytics and AI, they are increasingly finding themselves caught in a complex web of extract, transform, and load (ETL) pipelines—the traditional backbone of data integration. While these pipelines still serve their purpose, they’ve also become a costly bottleneck, consuming valuable staff time and resources that could be better spent on innovation. Now, zero-ETL integrations are simplifying how businesses handle data integration. Zero-ETL can eliminate the need for complex data pipelines while still maintaining seamless data flow between your operational databases and analytics environments, including data warehouses, data lakes, and the combination of these into lakehouses.

Thousands of AWS customers have used zero-ETL to process petabytes of data with thousands of integrations. AWS customers are using integrations with services such as Amazon Aurora, Amazon Relational Database Service (Amazon RDS), Amazon Redshift, Amazon DynamoDB, and Amazon SageMaker, along with multiple third-party software as a service (SaaS) applications. These zero-ETL integrations are transforming data integration from a technical burden into a strategic advantage, so that businesses can focus on deriving actionable insights from their data.

The evolution of data integration

Traditionally, organizations have relied on ETL processes to move data between operational databases and analytics systems. This approach, while functional, presents several key challenges that can hinder an organization’s ability to derive timely insights from their data.

Building and maintaining ETL pipelines requires significant engineering resources, often diverting talent from core business initiatives. These pipelines need constant attention, updates, and optimization, creating an ongoing operational burden. As data volumes grow, updates happen faster, and schemas evolve, the complexity of these pipelines increases exponentially.

Pipeline failures can cause delays in data availability, impacting decision-making processes. When a pipeline breaks, it can take hours or even days to diagnose and fix the issue, during which time critical business decisions might be made with outdated information. This lag between data creation and availability for analysis can be a significant competitive disadvantage in fast-moving industries.

Complex transformations introduce potential points of failure, increasing the risk of data inconsistencies. Each transformation step is an opportunity for errors to creep in, whether through bugs in the transformation logic or unexpected edge cases in the data. Making sure of data quality and consistency across these transformations requires rigorous testing and validation processes.

Furthermore, as organizations add new data sources, the operational overhead of managing multiple pipelines increases exponentially. Each new source typically requires its own pipeline, complete with custom logic for extraction, transformation, and loading. This proliferation of pipelines can quickly become unwieldy, making it difficult to maintain a coherent data strategy across the organization.

How zero-ETL makes data accessible for analytics

AWS zero-ETL integrations provide automated, fully managed data replication from both AWS services and third-party applications to AWS data warehouses, data lakes, and lakehouses without requiring custom pipeline development. This innovative approach offers numerous benefits across several key areas, fundamentally changing how organizations approach data integration.

Simplified data architecture

Zero-ETL integrations offer low-code or no-code setup, which means that organizations can quickly establish data access and flows without specialized expertise. This democratization of data integration means that teams across the organization can set up and manage their own data integration, reducing bottlenecks and accelerating time-to-insight.

Zero-ETL integrations automatically handle data definition languages (DDLs), schema changes, and data type mapping, so that data in your analytics store is correct and complete. This data is immediately available for business consumption, helping to ensure consistency between source and target systems. This automatic mapping significantly reduces the risk of errors that can occur with manual mapping processes, helping to ensure that data types and structures are correctly translated between systems.

Built-in monitoring and error handling capabilities provide visibility into the replication process and help maintain data integrity. Administrators can set up alerts for specific conditions, such as replication lag or failed transfers, allowing for proactive management of the data integration process.

Zero-ETL integrations automatically handle full load and ongoing changes through change data capture (CDC) for quick access to the latest data. Organizations can use this dual capability to migrate existing data while also making sure that new data is continuously replicated, providing a seamless transition to the new integration model.

Near real-time analytics

With zero-ETL integrations, data is typically available in the target system within seconds or minutes of updates in the source system. This near real-time capability supports even high-volume transactional workloads, enabling timely insights for fast-moving businesses. For example, an ecommerce company can analyze purchase patterns almost immediately, enabling real-time inventory management and personalized recommendations.

The solution maintains consistent performance at scale, accommodating growing data volumes without degradation. As businesses grow and data volumes increase, the zero-ETL integration scales automatically, keeping performance consistent even as the demands on the system increase.

Built-in fault tolerance and recovery mechanisms help ensure high availability and data consistency. If an issue occurs during replication, manual or automatic retries of failed operations help resume from the last successful point, minimizing data loss and helping to ensure consistency between source and target systems.

Reduced operational burden

By eliminating the need for custom pipeline maintenance, zero-ETL integrations free up valuable engineering resources. Data engineers can focus on higher-value tasks such as data modeling, advanced analytics, and machine learning, rather than spending time on routine pipeline maintenance.

There is no additional infrastructure to manage, reducing complexity and cost. The zero-ETL integration runs on AWS-managed infrastructure, eliminating the need for customers to provision and manage servers, storage, or networking components for data integration.

The system automatically handles schema changes, adapting to evolving data structures without manual intervention. When a new column is added to a source table, for example, the zero-ETL integration will automatically detect this change and update the target schema accordingly, helping to ensure that the data remains in sync without any manual effort.

Native integration with AWS security controls helps ensure that data remains protected throughout the replication process. This includes support for encryption at rest and in transit, and integration with AWS Key Management Service (AWS KMS) for compliance with various regulatory standards.

Customer success with Zero-ETL

Since launch, zero-ETL integrations have seen rapid customer adoption. The versatility and benefits of zero-ETL integrations are demonstrated through diverse customer implementations across industries.

Yossi Shlomo, Director of Payment Systems Architecture at MassPay, a leading global payment solutions provider, stated, “Zero-ETL has been transformative for teams at MassPay. By using Amazon Aurora MySQL-Compatible Edition zero-ETL integration with Amazon Redshift, we’ve streamlined data flow from our core payment systems into analytics environments used for fraud detection, compliance case management, and business insights. This shift reduced latency by >90% and gives our teams near-instant access to critical data to optimize processes and decisions.” Because of this dramatic improvement in data freshness and availability, MassPay can make more timely and informed decisions, improving their service to customers and their competitive position in the market.

Available AWS service Integrations

AWS currently offers zero-ETL integrations designed to seamlessly connect popular AWS database services with Amazon Redshift, a fully managed data warehouse service. These include Amazon Aurora MySQL-Compatible, Amazon Aurora PostgreSQL-Compatible Edition, Amazon RDS for MySQL, and Amazon DynamoDB. This means that organizations can use the strengths of each service—the transactional capabilities of Aurora and Amazon RDS, the flexibility of DynamoDB, and the analytical power of Amazon Redshift—while minimizing the complexity of data movement between these systems.

Third-party integration support

Zero-ETL integrations have expanded beyond AWS services to support a wide range of third-party data too. AWS has zero-ETL integrations with sources including SAP OData, Salesforce, Salesforce Marketing Cloud Account Engagement, ServiceNow, Zendesk, and Zoho CRM, plus Facebook Ads and Instagram Ads. Targets include Amazon Redshift and a lakehouse with Amazon SageMaker.

Recent updates include:

Traditional relational databases from various vendors can also link to a lakehouse through zero-ETL integrations. This comprehensive support means that organizations can consolidate data from virtually any source into their AWS analytics environment without building custom integration pipelines. By using zero-ETL to break down data silos—even between multiple vendors’ solutions—and simplifying the data integration process, organizations can focus on deriving insights rather than managing complex data movements.

Additional integrations are in development to support more AWS services and data sources, further expanding the ecosystem. AWS is committed to continually expanding the range of zero-ETL integrations, responding to customer needs and evolving data landscapes.

Advanced features and capabilities of AWS zero-ETL

AWS zero-ETL capabilities include several sophisticated features that set them apart from other clouds. For example, by using the refresh interval control, you can customize how frequently data is synchronized, helping to ensure that analytics are based on data that is as current as necessary for each use case. Meanwhile, History Mode maintains historical versions of data, enabling trend analysis, insightful dashboards, and meeting audit requirements. You can also create type 2 slowly changing dimensions (SCD 2) tables in Amazon Redshift.

You can use the data filtering capabilities to selectively replicate specific objects and data subsets, optimizing storage use and focusing on the most relevant data. Comprehensive logging and monitoring features provide visibility into data movement and system health, so that administrators can quickly identify and address any issues.

You can also combine two primary integration approaches. Zero-ETL provides full data replication (movement) for comprehensive analytics in a central repository, complementing federation allows querying data in place when real-time access to source data is critical. You can use this flexibility to tailor your data integration strategy to your organization’s specific needs and use cases.

Getting started with zero-ETL

To begin using zero-ETL integrations, you should first identify your source database and target analytics service. This involves assessing your current data architecture and determining which data flows would benefit most from a zero-ETL approach.

Next, you need to configure the necessary permissions and networking requirements. This typically involves setting up either an AWS Identity and Access Management (IAM) identity or single sign-on using AWS IAM Identity Center and making sure that the source and target services can communicate securely.

As shown in the following image, after the prerequisites are in place, creating the integration is a click-through experience within the AWS Management Console. The intuitive interface guides you through the process, prompting you to specify source and target details, select tables for replication, and configure any additional options.

Salesforce objects for zero-ETL

After setup, you can monitor replication status and performance to help ensure optimal operation. AWS provides detailed metrics and logs to help you track the health and performance of your zero-ETL integrations.

For detailed setup instructions, visit the AWS documentation for zero-ETL integrations, which provides step-by-step guides for each supported integration.

What’s ahead for zero-ETL

AWS has an active roadmap for support of additional AWS services and data sources, expanding the reach of zero-ETL integrations so that more customers can benefit from simplified data integration across a broader range of use cases.

Zero-ETL integrations represent a fundamental shift in how organizations approach data integration. Without the complexity of ETL pipelines, customers can focus on deriving value from their data rather than managing infrastructure. This approach aligns with the AWS commitment to simplifying cloud operations and empowering customers to innovate faster.

To learn more about zero-ETL integrations and how they can benefit your organization, see the following topics:

Get started today and discover how you can streamline your data operations and unlock the full potential of your data with AWS zero-ETL integrations.


Nikki Rouda works in product marketing at AWS. He has many years experience across a wide range of IT infrastructure, storage, networking, security, IoT, analytics, and modern applications.

The Amazon SageMaker lakehouse architecture now automates optimization configuration of Apache Iceberg tables on Amazon S3

Post Syndicated from Tomohiro Tanaka original https://aws.amazon.com/blogs/big-data/the-amazon-sagemaker-lakehouse-architecture-now-automates-optimization-configuration-of-apache-iceberg-tables-on-amazon-s3/

As organizations increasingly adopt Apache Iceberg tables for their data lake architectures on Amazon Web Services (AWS), maintaining these tables becomes crucial for long-term success. Without proper maintenance, Iceberg tables can face several challenges: degraded query performance, unnecessary retention of old data that should be removed, and a decline in storage cost efficiency. These issues can significantly impact the effectiveness and economics of your data lake. Regular table maintenance operations help ensure your Iceberg tables remain high performing, compliant with data retention policies, and cost-effective for production workloads. To help you manage your Iceberg tables at scale, AWS Glue automated those Iceberg table maintenance operations: compaction with sort and z-order and snapshots expiration and orphan data management. After the launch of the feature, many customers have enabled automated table optimization through AWS Glue Data Catalog to reduce operational burden.

The Amazon SageMaker lakehouse architecture now automates optimization of Iceberg tables stored in Amazon S3 with catalog-level configuration, optimizing storage in your Iceberg tables and improving query performance. Previously, optimizing Iceberg tables in AWS Glue Data Catalog required updating configurations for each table individually. Now, you can enable automatic optimization for new Iceberg tables with one-time Data Catalog configuration. Once enabled, for any new table or updated table, Data Catalog continuously optimizes tables by compacting small files, removing snapshots, and unreferenced files that are no longer needed.

This post demonstrates an end-to-end flow to enable catalog level table optimization setting.

Prerequisites

The following prerequisites are required to use the new catalog-level table optimizations:

Enable table optimizations at the catalog level

The data lake administrator can enable the catalog-level table optimization on the AWS Lake Formation console. Complete the following steps:

  1. On the AWS Lake Formation console, choose Catalogs in the navigation pane.
  2. Select the catalog to be enabled with catalog-level table optimizations.
  3. Choose Table optimizations tab, and choose Edit in Table optimizations, as shown in the following screenshot.

setup-catalog-level-optimizations

  1. In Optimization options, select Compaction, Snapshot retention, and Orphan file deletion, as shown in the following screenshot.

enable-optimizations

  1. Select an IAM role. Refer to Table optimization prerequisites for permissions.
  2. Choose Grant required permissions.
  3. Choose I acknowledge that expired data will be deleted as part of the optimizers.

After you enable the table optimizations at the catalog level, the configuration is displayed on the AWS Lake Formation console, as shown in the following screenshot.

optimizations-configuration

When you select an Iceberg table registered in the catalog, you can confirm that the table optimizations configuration is inherited from the table view because Configuration source shows catalog, as shown in the following screenshot.

catalog-level-optimizations

The table optimizations history is displayed on the table view. The following result shows one of the compaction runs by the table optimizations.

binpack-compaction-result

The catalog-level table optimizations for all databases and Iceberg tables are now enabled.

Customize setting of table optimizations at both the catalog and table-level

Although the catalog-level optimization applies common settings across all databases and Iceberg tables in your catalog, you might want to apply different strategies for specific Iceberg tables. You can use AWS Glue Data Catalog to enable both catalog-level and table-level optimizations based on specific table characteristics and access patterns. For example, in addition to configuring the catalog-level compaction with the bin-pack strategy for general-purpose Iceberg tables, you can apply the sort strategy at the table-level to tables with frequent range queries on timestamp columns.

This section shows configuring catalog-level and table-specific optimizations through a practical scenario. Imagine a real-time analytics table with frequent write operations that generates more orphan files due to constant metadata updates. Users also run selective queries filtering specific columns, which makes sort-order strategy preferable. Complete the following steps:

  1. Select another Iceberg table in the same catalog as before to configure the table-level optimizations on the AWS Lake Formation console. At this point, the catalog-level table optimizations are configured for this table.
  2. Choose Edit in Optimization configuration, as shown in the following screenshot.

new-optimizations-configuration

  1. In Optimization options, choose Compaction, Snapshot retention, and Orphan file deletion.
  2. In Optimization configuration, choose Customize settings.
  3. Select the same IAM role.
  4. In Compaction configuration, select Sort, as shown in the following screenshot. Also configure 80 files to Minimum input files, which is a threshold of the number of files to trigger the compaction. To configure Sort, a sort order needs to be defined in your Iceberg table. You can define the sort order with Spark SQL such as ALTER TABLE db.tbl WRITE ORDERED BY <columns>.

sort-config

  1. In Snapshot retention configuration and Snapshot deletion run rate, select Specify a custom value in hours. Then, configure 12 hours to the interval between two deletion job runs, as shown in the following screenshot.

snapshot-retention

  1. In Orphan file deletion configuration, configure 1 day to Files under the provided Table Location with a creation time older than this number of days will be deleted if they are no longer referenced by the Apache Iceberg Table metadata.

orphan-deletion

  1. Choose Grant required permissions.
  2. Choose I acknowledge that expired data will be deleted as part of the optimizers.
  3. Choose Save.
  4. The Table optimization tab on the AWS Lake Formation console displays the custom setting of table optimizers. In Compaction, Compaction strategy is configured to sort and Minimum input files is also configured to 80 files. In Snapshot retention, Snapshot deletion run rate is configured to 12 hours. In Orphan file deletion, Orphan files will be deleted after is configured to 1 days, as shown in the following screenshot.

new-table-level-optimizations

The compaction history shows sort as its table-level compaction strategy even if the strategy in the catalog-level is configured to binpack, as shown in the following screenshot.

sort-compaction-result

In this scenario, the table-specific optimizations are configured along with the catalog-level optimizations. Combining the table and catalog-level optimizations means you can more flexibly manage your Iceberg table data deletions and compactions.

Conclusion

In this post, we demonstrated how to enable and manage using Amazon SageMaker lakehouse architecture with AWS Glue Data Catalog’s catalog-level table optimization feature for Iceberg tables. This enhancement significantly simplifies the management of Iceberg tables because you can enable automated maintenance operations across all tables with a single setting. Instead of configuring optimization settings for individual tables, you can now maintain your entire data lake more efficiently, reducing operational overhead while ensuring consistent optimization policies. We recommend enabling catalog-level table optimization to help you maintain a well-organized, high-performing, and cost-effective data lake while freeing up your teams to focus on deriving value from your data.

Try out this feature for your own use case and share your feedback and questions in the comments. To learn more about AWS Glue Data Catalog table optimizer, visit Optimizing Iceberg tables.
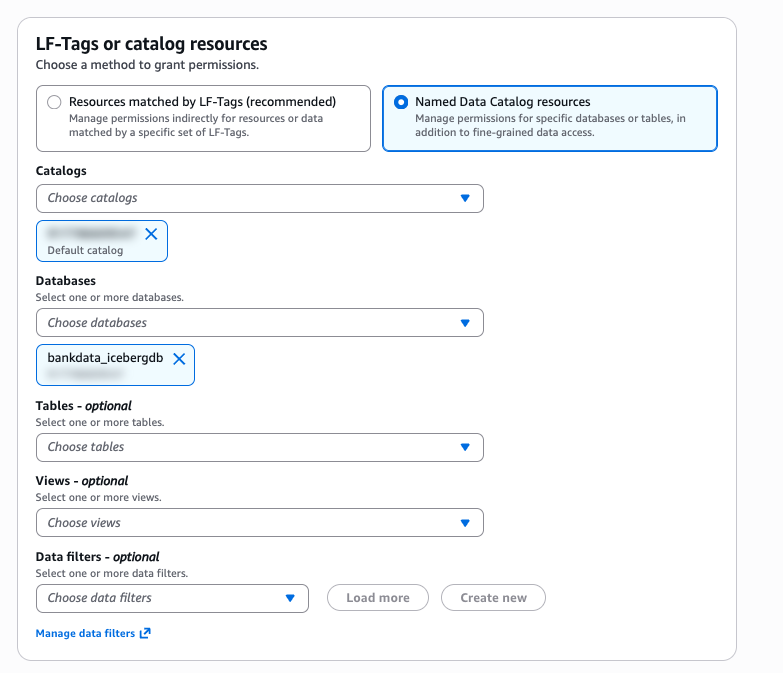
Acknowledgment: A special thanks to everyone who contributed to the development and launch of catalog level optimization: Siddharth Padmanabhan Ramanarayanan, Dhrithi Chidananda, Noella Jiang, Sangeet Lohariwala, Shyam Rathi, Anuj Jigneshkumar Vakil, and Jeremy Song.


About the authors

Tomohiro Tanaka is a Senior Cloud Support Engineer at Amazon Web Services (AWS). He’s passionate about helping customers use Apache Iceberg for their data lakes on AWS. In his free time, he enjoys a coffee break with his colleagues and making coffee at home.

Noritaka Sekiyama is a Principal Big Data Architect with AWS Analytics services. He’s responsible for building software artifacts to help customers. In his spare time, he enjoys cycling on his road bike.
Sandeep Adwankar is a Senior Product Manager at Amazon Web Services (AWS). Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products customers can use to improve how they manage, secure, and access data.
Siddharth Padmanabhan Ramanarayanan is a Senior Software Engineer on the AWS Glue and AWS Lake Formation team, where he focuses on building scalable distributed systems for data analytics workloads. He is passionate about helping customers optimize their cloud infrastructure for performance and cost efficiency.