Tag Archives: Customer Solutions

Revenue NSW modernises analytics with AWS, enabling unified and scalable data management, processing, and access

Post Syndicated from Saeed Barghi original https://aws.amazon.com/blogs/big-data/revenue-nsw-modernises-analytics-with-aws-enabling-unified-and-scalable-data-management-processing-and-access/

Revenue NSW, in Australia, is New South Wales (NSW) state’s principal revenue management agency and aspires to be the world’s most innovative and customer-centric revenue agency. Revenue NSW exists to administer grants, resolve fines, and collect revenue to fund essential state services for the over 8 million people of NSW in a fair, efficient, and timely manner.

Analytics at Revenue NSW plays a key role in enabling the organization’s goals and purpose by delivering reliable, secure, and authoritative insights. These insights are key to:

  • Understanding customer attributes to enable empathetic and informed actions
  • Supporting policy development
  • Assisting in the sequencing of millions of decisions
  • Maintaining compliance and education
  • Fostering transparency by providing open data and insights directly to the public

The challenge

Revenue NSW Analytics consumes data from a multitude of operational databases and real-time interfaces and through internally generated reports and files received from external data partners such as other government departments and agencies. The varying technologies, formats, and complexities of these data sources created friction and inefficiencies in data transformation, consolidation, and analysis in an environment that is often time-critical. In addition, these analytics systems were previously hosted on dedicated hardware on-premises that was nearing end-of-life and wasn’t easy to scale efficiently. To address these challenges, Revenue NSW Analytics used their partnership with AWS to build a strategic, unified, scalable, frictionless and modern data environment to help them standardize data transformation and consolidation pipelines from the hundreds of data sources. Additionally, the modern data environment must provide a single source of truth and enable secure and seamless access to the data through a unified SQL interface regardless of the data’s original format or technology.

After understanding other offerings, Revenue NSW Analytics decided on a proof of concept (PoC) using Amazon Web Services (AWS) cloud-based services, including Amazon Redshift. The key goals of the PoC were to assess the completeness of the solution, its performance, and the potential change in total cost of ownership compared to their on-premises setup.

Amazon Redshift, with its integration options, columnar storage, and massively parallel processing (MPP) architecture, offered the desired end-state solution. Tests demonstrated a typical speed increase between 5- and 50-fold in query execution, with many results 100 times faster than the existing on-premises solution. Amazon Redshift also performed significantly better compared with other cloud-based solutions, offering up to 6 times better performance. The success of the initial PoC led Revenue NSW Analytics to further collaborate with AWS, working towards developing a prototype that incorporated Amazon Redshift alongside various data ingestion patterns.

The solution

To simplify data ingestion from the operational databases—which run on different database engines including Oracle, PostgreSQL, and Microsoft SQL—Revenue NSW Analytics used AWS Database Migration Service (AWS DMS) to perform a bulk initial load, followed by capturing ongoing changes from these databases into Amazon Redshift in near real time.

For data from Salesforce’s real-time API, Revenue NSW Analytics used Amazon AppFlow to automate the continuous pulling and ingesting of data into Amazon Redshift.

The hundreds of structured and semi-structured data files were handled using AWS Glue. These files are regularly uploaded to Amazon Simple Storage Service (Amazon S3), triggering the relevant AWS Glue extract, transform, and load (ETL) jobs in an event-based architecture to transfer the data into Amazon Redshift.

To facilitate repeatability and enable iteration, Revenue NSW Analytics used infrastructure-as-code (IaC) and continuous integration and delivery (CI/CD) pipelines to deploy the different components of the solution.

The following is a high-level architecture demonstrating how these different components and services fit together.

Along with standardization and unified access, the success criteria of the new data environment included the ease of transition, consolidation of processes to the new standardised pipelines, scalability, language uniformity, and availability. The combination of supporting standard SQL, AWS DMS, and Amazon AppFlow low-code capabilities, and supporting Python in AWS Glue, a popular programming language, played a crucial role in facilitating the successful transition and adoption of the cloud-based data environment.

Other success factors of this environment include the ability to work within current budgets, and the extendibility and modularity of the solution. As shown in the preceding high-level architecture, the solution runs on multiple building blocks that are decoupled, modular, and either serverless—like AWS Glue—or managed services that support seamless scalable configurations that don’t require rebuilds. This allowed Revenue NSW Analytics to start small with each use case, expand and grow as required, and pay only for what they need.

Moreover, with the new cloud-based data environment, Revenue NSW Analytics can access to up-to-date data in near real time, which is essential to fulfilling critical use cases such as information requests and assisting with compliance case identification. The automated data ingestion pipelines removed much of the boilerplate and heavy lifting, allowing Revenue NSW teams to work more efficiently and focus on the differentiators of their business, and in some cases, shorten workflow times from months to weeks or days.

Another significant factor contributing to the project’s success is the people at the heart of Revenue NSW Analytics. The teams allocated to own and deliver this platform are cross-functional, with adjoining responsibilities and skills, and were prepared through multiple in-person and online training sessions. The teams were empowered to trial individual services to deliver new use cases and iterate on the solution to learn from successes and innovate progressively. This approach, together with support Revenue NSW received from AWS specialist solution architects, helped to minimize the risk of knowledge gaps that often arise when separate teams are responsible for building and operating a system.

The hard work of the Analytics team, the investment of Revenue NSW Analytics leadership in its people, and the continuous support from AWS can truly be seen throughout the delivery of the data environment, resulting in the achievement of the intended outcomes.

Conclusion and call to action

Since going live with their cloud-based data environment on AWS, Revenue NSW has onboarded dozens of analysts who can get more done in less time. This is a result of establishing a single source of truth from different data sources in Amazon Redshift, so that analysts and data consumers don’t need to shop around to find the data that they need to complete their tasks. This new data environment also provides Revenue NSW with the ability to create improved conditions for:

  • Increasing agility by exposing reusable, trusted data services for people and AI
  • Empowering operational systems with services best provided by analytical approaches
  • Decommissioning heritage, costly infrastructure and data practices.

Successful delivery of the cloud-based data environment on AWS has led to further collaboration between AWS and Revenue NSW. This includes exploring the adoption of AI and machine learning (AI/ML) and generative AI to further improve the delivery of services for the people of NSW.

To learn more about customer success stories like this or how to get started with building a data environment on AWS, contact your AWS account team. You can read about similar customers by browsing Customer Success Stories on our website.


About the authors

Saeed BarghiSaeed Barghi is a Sr. Specialist Solutions Architect at Amazon Web Services (AWS) specializing in architecting enterprise data platforms and AI solutions. Based in Melbourne, Australia, Saeed works with public sector customers in Australia and New Zealand and helps his customers build fit-for-purpose and future-proof data platforms and AI solutions.

Miroslaw (Mick) Mioduszewski is the Director of Analytics at Revenue NSW Department of Customer service in NSW. He held multiple C-level roles in private and public companies as well as government, e.g. COO and CIO, as well as serving as company director. Mick holds computer science and business degrees, is a fellow of the Australian Institute of Company Directors and an industry fellow at the University of technology, Sydney.

Moha Alsouli is a Public Sector Solutions Architect at Amazon Web Services (AWS) in Sydney. He is dedicated to supporting state and local government customers deliver citizen services, through solution design, reviews, optimisation, and architecture guidance. Moha is also specialising in generative artificial intelligence (AI) on AWS.

How Scale to Win uses AWS WAF to block DDoS events

Post Syndicated from Ben "Fuzzy" Shonaldmann original https://aws.amazon.com/blogs/architecture/how-scale-to-win-uses-aws-waf-to-block-ddos-events/

This is a guest post coauthored by Ben “Fuzzy” Shonaldmann of Scale to Win.

Scale to Win was created for organizers by organizers. Born out of the 2020 election cycle, a group of friends and former colleagues came out of a whirlwind presidential primary season with frustrations and ideas to improve campaign technology. With extensive outreach experience on high-profile presidential campaigns such as Biden/Harris 2020, Bernie 2016 and 2020, Warren 2020, and Clinton 2016, we knew the power of organizing. We saw how conversations—neighbor to neighbor, friend to friend, volunteer to voter—could transform communities and drive movements. Yet, the tools available for voter contact programs regularly fell short of our needs. We built and launched our first product in April 2020, a peer-to-peer (P2P) texting tool. We’ve since added a dialer tool that allows organizations to easily call voters, and Scale to Win Text, an all-in-one texting tool for organizing and fundraising.

During the 2024 US presidential election campaign season, we were the target of distributed denial of service (DDoS) events. These events reached peaks of over 2 million requests per second from nearly ten thousand unique IPs. After a brief window of downtime at the start of these events, Scale to Win partnered with Amazon Web Services (AWS) to implement AWS WAF, AWS Shield Advanced, and Amazon CloudFront to mitigate these targeted DDoS events.

One key element of our defense was AWS WAF support for Completely Automated Public Turing test to tell Computers and Humans Apart (CAPTCHA) to automatically present a challenge to suspicious-looking clients. We used this to provide a per-IP rate limit for traffic we expected to see from legitimate clients behind a single IP. For IPs that exceed this rate limit, we present a CAPTCHA and provide a higher rate limit to the maximum amount of traffic we expect to come from a single IP, like a campaign office or college campus.

However, the AWS WAF out-of-the-box CAPTCHA had an important caveat—it doesn’t provide protection against an event using a token that is solved and distributed across a network of machines behind multiple IPs. To prevent this class of event, AWS WAF users need to identify CAPTCHA tokens that are being used from multiple IPs and automatically block this traffic.In this post, you’ll learn how Scale to Win configured our network topology to maximize DDoS protection capacity, configured AWS WAF to block DDoS events, segmented machine-to-machine and browser-to-machine traffic to target CAPTCHA interventions, and blocked token reuse across IP addresses.

Network Topology Overview

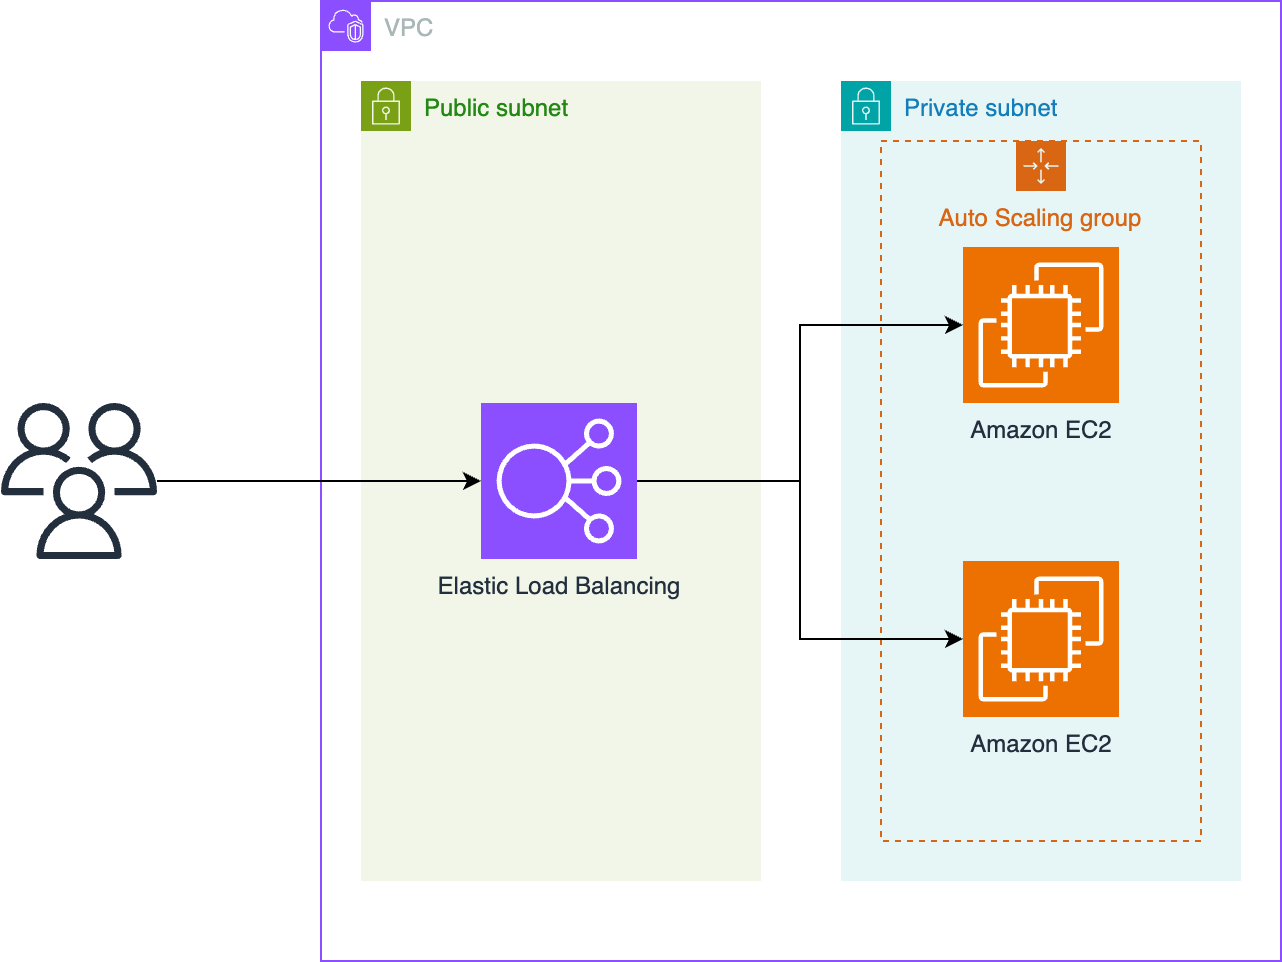
The Scale to Win application runs behind an Application Load Balancer (ALB) that serves as the single point of entry to our application servers. Before implementing AWS WAF, our DNS records resolved to the ALB as shown in the following diagram. The diagram shows a path from users to Elastic Load Balancing to an auto scaling group of Amazon Elastic Compute Cloud (Amazon EC2) instances.

Diagram of a VPC with public and private subnets, Elastic Load Balancing, and Amazon EC2 instances

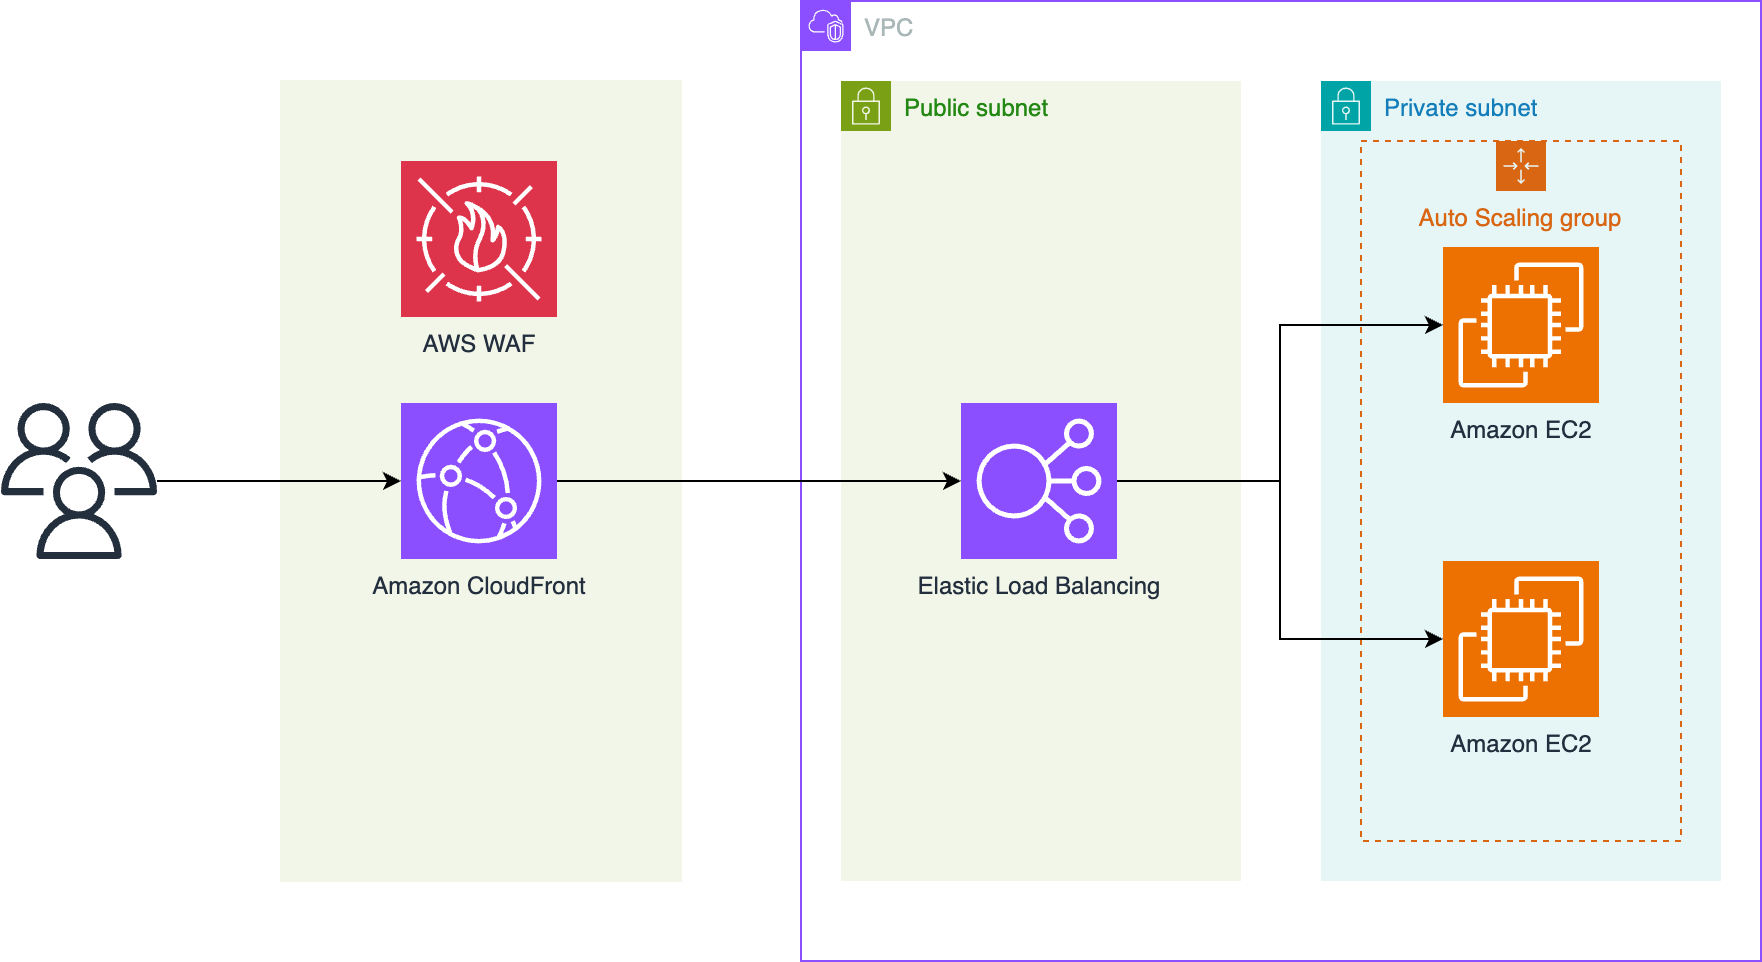
The recommended pattern for using AWS WAF to protect against DDoS events is to instead route traffic through a CloudFront distribution as shown in the following diagram. The diagram shows a path from users to CloudFront with AWS WAF to Elastic Load Balancing to an auto scaling group of EC2 instances.

VPC architecture with AWS WAF, CloudFront, Load Balancing, and EC2 instances

Using this topology, we can take advantage of the following benefits:

  1. The capacity of CloudFront to handle network-layer events sending TCP traffic that aren’t valid HTTP requests is greater than ALB capacity. Network-level protections are strongest when applied by CloudFront before passing traffic to the ALB.
  2. The edge deployment of AWS WAF has higher quotas and capacity than Regional deployments. AWS scales AWS WAF capacity one-to-one with CloudFront capacity, so AWS WAF always has enough capacity to handle incoming traffic.
  3. When implementing a geographic based block strategy, such as blocking specific countries, CloudFront provides a geographic restriction feature. In event patterns we observed, over half of malicious traffic originated from countries that we blocked completely in CloudFront, resulting in cost savings on our AWS WAF deployment.

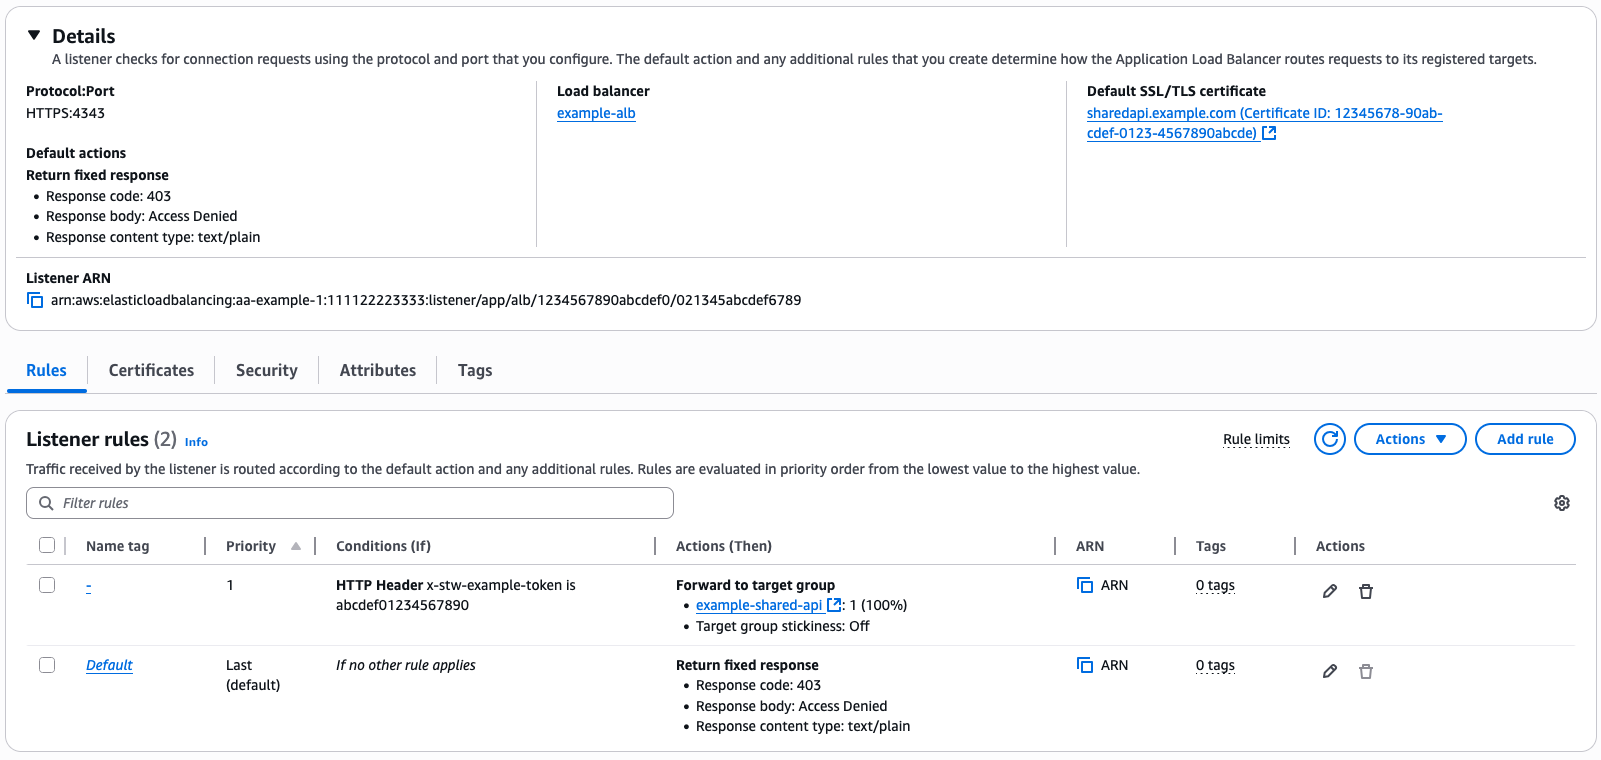
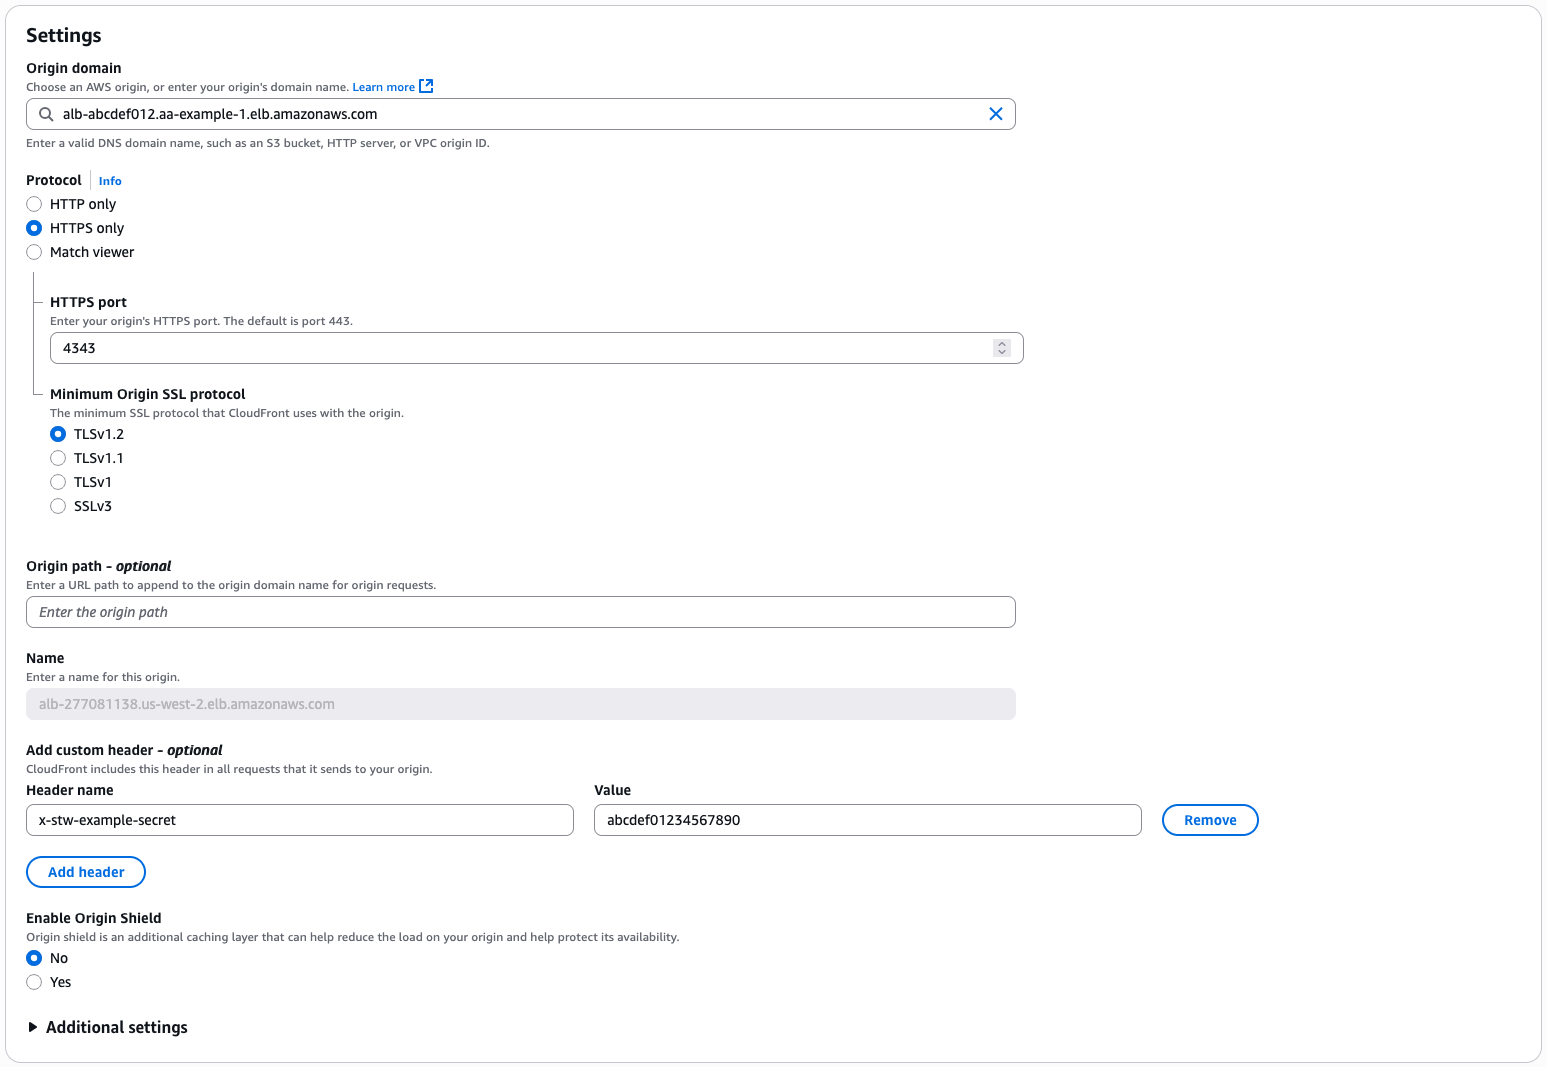
To prevent threat actors from bypassing our CloudFront distribution and AWS WAF, we implemented a security group that allows traffic only from CloudFront edge IP addresses using the managed prefix list to prevent direct connections to the ALB. We then configured the ALB to require a secret, pre-shared token in a request header, for example, our header x-stw-example-secret. We configured the CloudFront distribution to add that request header when forwarding traffic to the origin. This secret isn’t logged to Application Load Balancer logs but is logged to AWS CloudTrail when setting or updating the CloudFront or ALB configuration. It’s possible to rotate this secret on a schedule by generating a random password with AWS Secrets Manager with an AWS Lambda function to update the CloudFront origin configuration and ALB listener configuration, as shown in the following two screenshots. This shared secret between the CloudFront distribution and ALB means that an event can’t bypass the security group control by configuring its own CloudFront distribution with our ALB as an origin.

The following screenshot shows configuration of the Application Load Balancer, showing a priority-1 rule to route traffic to our target group only if the x-stw-example-secret is correct. A default rule returns a 403 if it’s not correct.

AWS Elastic Load Balancing configuration details, displaying the protocol, port, load balancer name, and SSL/TLS certificate for a listener.

The following screenshot shows CloudFront origin settings, showing a custom header configuration to add the shared secret to requests to the origin.

AWS CloudFront origin settings showing domain, protocol, SSL, and custom header options

Configuring AWS WAF rules

We use two approaches to identify and block malicious DDoS traffic, a heuristic approach and a hard limit approach.

For the heuristic approach, we observe event traffic in AWS WAF sample requests and AWS WAF logs, identify patterns in the event, and block those specific patterns. To use this tactic in your own AWS WAF configuration, first identify a characteristic that is common to all or most event traffic but rare in legitimate traffic, like a HTTP header or query parameter. Create a AWS WAF rule that blocks the traffic. Using the Count rule action is helpful to test your rule and find false-positive and false-negative rates by correlating requests that match the rule with IPs that are sending high volumes of traffic. You can query AWS WAF logs with Amazon Athena to find these correlations. When you’re satisfied with your false-positive and false-negative rates, set the rule action to Block to actively block the matched traffic.

A motivated threat actor will notice the event is being blocked and randomize these parameters to bypass your rules. For example, they might replay legitimate session parameters, so that request URIs, query parameters, and request bodies are identical to legitimate traffic. Ultimately, the heuristic approach is a useful tool, and a good reason to set up logging and Athena to quickly query your AWS WAF logs, but it’s a solution that requires active reconfiguration of your AWS WAF as event patterns change.

One specific heuristic that’s worth calling out is JA4 fingerprints and their predecessor, JA3 fingerprints. A JA4 fingerprint is a hash of several parameters presented by TLS clients in the client hello packet. JA4 fingerprints roughly correspond to the specific TLS client parameters of the request, so they’re usually stable for a specific type of client. For example, a specific version of Google Chrome on a particular operating system has a fingerprint, but a version on a different operating system would have a different fingerprint. This makes JA4 fingerprints a useful heuristic for blocking malicious traffic because the botnet sending the traffic is likely to have a small number of different fingerprints. However, there are two caveats with blocking requests based on JA4 fingerprints:

  1. Threat actors might have the same JA4 fingerprint as legitimate users. In our case, we saw malicious traffic with the same fingerprint as a common NodeJS API client and were unable to block that fingerprint without blocking legitimate API clients.
  2. A sophisticated threat actor can randomize some of the TLS connection parameters, such as the order of TLS extensions in the client hello packet, which is done by threat actors to avoid JA3 fingerprint blocking and some browsers to preserve user privacy. Although the newer JA4 specification reduces some randomization elements, the fundamental challenge remains—because end users maintain control over the client hello packet, this creates an ongoing challenge of adaptation and response.

For the hard limit approach, we take advantage of request parameters that the event can’t fake, such as the source IP of the request. Although the source IP of a packet can be forged, these requests are dropped because they don’t successfully complete the TCP or TLS handshake. You can create AWS WAF rules that limit how much traffic can be sent from a single source IP using rate-based rule statements, setting the limit above what a legitimate user would send but below what the event needs to be effective.

The simplest approach with rate-based rule statements would be to have a single limit in the AWS WAF policy, but this has challenges. First, we have APIs that receive high volumes of machine-to-machine traffic. For example, we place outbound phone calls using Twilio, and Twilio sends tens of thousands of webhooks to our API per second to relay delivery status, sometimes from a single Twilio IP. Also, our application is often used by campaign offices or student-led phone banks on college campuses that might have hundreds of users behind a single or handful of IPs, so we can’t assume that a single IP is being used by a single user to calculate our acceptable rates of traffic.

Segmenting human and machine traffic

To address these challenges, we structure our AWS WAF rules to segment human and machine traffic. We do this by request path: AWS WAF rules can match based on request path, so we have a set of rules for machine traffic based on the webhook URLs or API paths where we expect machine traffic. For all other paths, we assume the traffic originates from a user visiting the site from their browser.

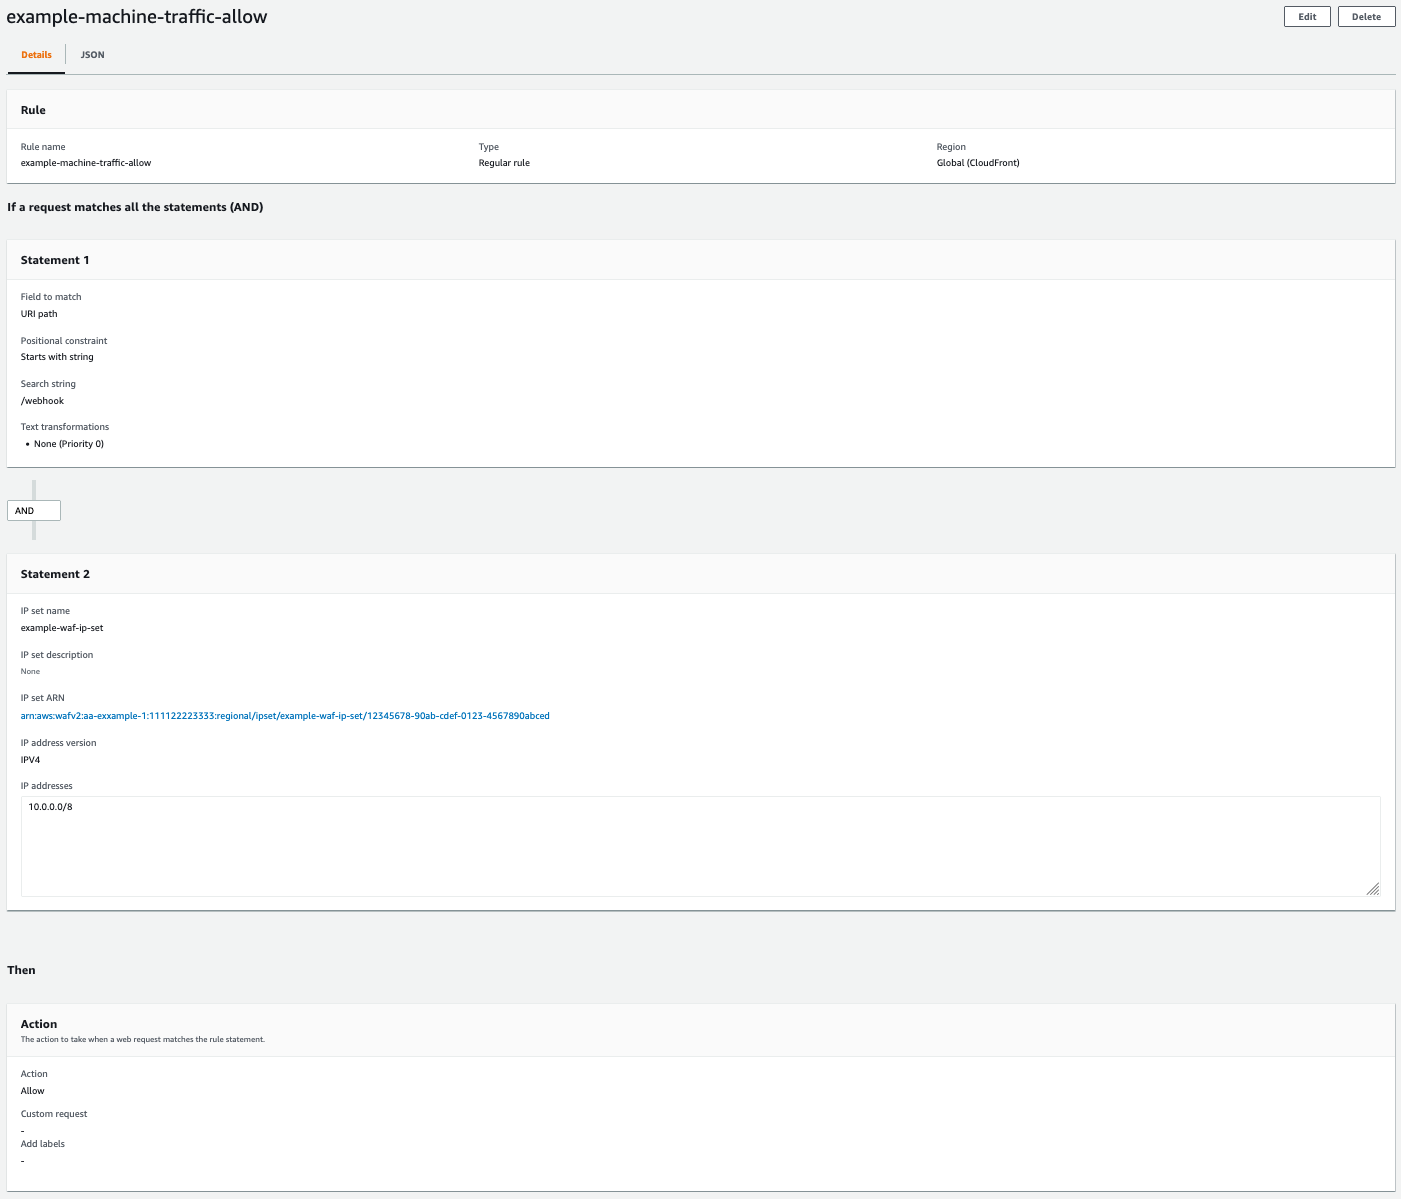
For machine traffic, we can’t use a CAPTCHA. Our API clients and the Twilio webhook infrastructure can’t solve the CAPTCHA, so we validate traffic differently. For our API clients, we set per-IP rate limits to what we expect from a single API client and return a 429 HTTP status when traffic exceeds our limit. We implement automatic retries to handle the occasional 429 error when sending above the limit. For Twilio or other webhook callbacks, we use published IPs from the service provider to create an IP set in AWS WAF. Then, we block requests to our webhook URL that don’t originate from the IP set. Not all service providers use static IPs—for Twilio specifically, we worked with their team to implement their Static Proxy feature to proxy webhook requests from a stable list of IPs. It also makes sense to implement API key authentication, request signing, and certificate-based authentication when possible for your machine traffic. For requests that originate from the IP set, we apply an Allow action in our AWS WAF rule to allow expected machine traffic through, as shown in the following screenshot. These rules allow high-volume machine-to-machine traffic through our AWS WAF configuration before we apply AWS WAF rules to block high volume user-based traffic. The following screenshot shows an example rule allowing expected machine-to-machine traffic.

WAF rule configuration showing machine traffic allow rules with URI path and IP settings

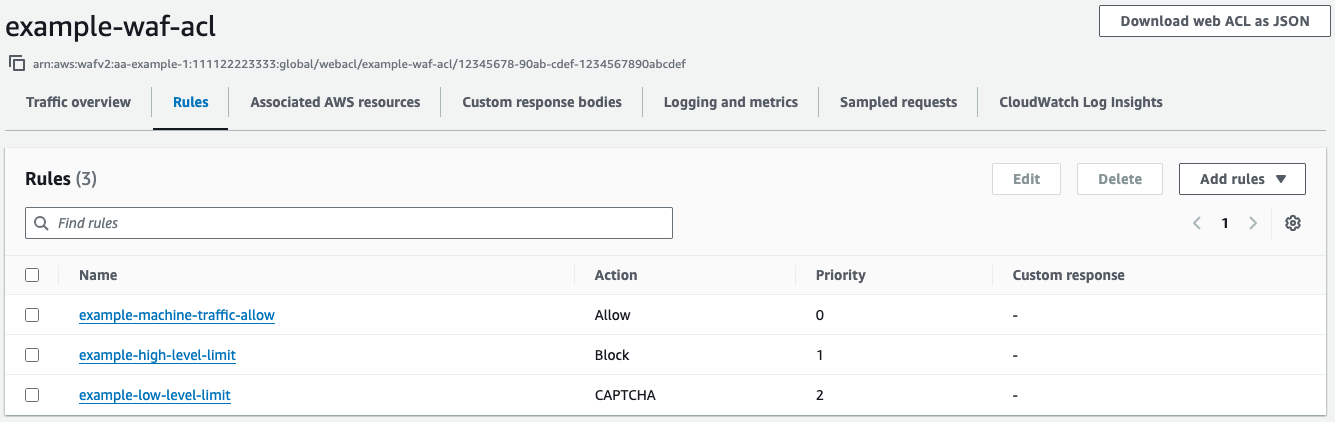
For our browser-based human traffic, we use a tiered rate limit strategy. We implement two tiers of rate limit: a low-level rate limit that corresponds to the maximum rate we expect two to three users to send, and a high-level rate limit that corresponds to the maximum rate we expect from a single IP with hundreds of users sharing the IP. Our low-level rule uses a CAPTCHA rule action when requests exceed the limit. Our high-level rule applies a Block action when requests exceed the limit. We set the high-level rate limit rule priority lower than the low-level rule so it’s processed first, as shown in the following screenshot.

AWS WAF web ACL interface displaying rules for traffic allow, block, and CAPTCHA actions

When a few users are sharing an IP address, they’re unlikely to hit either limit and can use the application without interruption. If a large group of users share an IP address, they’ll need to solve a CAPTCHA. After they solve it, they’re still limited by the high-level rate limit rule, which will prevent a threat actor from solving the CAPTCHA and then sending unlimited traffic using the token issued by AWS WAF.

Handling CAPTCHA on the frontend

For server-rendered applications, AWS WAF handles CAPTCHA challenges automatically through the following process:

  1. When a request matches a CAPTCHA rule without a valid token, AWS WAF presents an AWS managed CAPTCHA challenge page.
  2. Upon successful CAPTCHA completion, AWS WAF issues a Set-Cookie header containing the CAPTCHA token.
  3. Subsequent requests with valid CAPTCHA tokens can pass through AWS WAF for the configured immunity period.

For single-page applications (SPAs) or applications making API requests to a AWS WAF protected backend, additional implementation steps are required:

  1. Configure your frontend to detect blocked requests (HTTP 405 status code indicates CAPTCHA requirement).
  2. Present the CAPTCHA challenge to the user when required.
  3. Resubmit the original request after successful CAPTCHA completion.

The following sample code demonstrates how to implement CAPTCHA handling in a React component using the AWS WAF CAPTCHA JavaScript API:

import { useState, useRef, useEffect, ReactElement } from "react";

declare global {
  class CaptchaError extends Error {
    constructor(message: string);
    kind: "internal_error" | "network_error" | "token_error" | "client_error";
    statusCode?: number;
  }
  interface Window {
    AwsWafCaptcha: {
      renderCaptcha: (
        targetDiv: HTMLElement,
        options: {
          apiKey: string;
          onSuccess: (token: string) => void;
          onError: (err: CaptchaError) => void;
        }
      ) => void;
    };
    AwsWafIntegration: {
      fetch: typeof fetch;
    },
    awsWafCookieDomainList: string[];
  }
}

type DataLoading = {
  state: "loading";
};

type DataError = {
  state: "error";
  message: string;
};

type DataLoaded = {
  state: "loaded";
  data: any;
};

type Data = DataLoading | DataError | DataLoaded;

function MyComponent(): ReactElement {
  const [data, setData] = useState<Data>({ state: "loading" });
  const captchaDiv = useRef<HTMLDivElement>(null);

  useEffect(() => {
    void (async () => {
      try {
        const response = await window.AwsWafIntegration.fetch('/your/api/url');

        if (response.status === 405) {
          // The user needs to solve a captcha. 
          window.AwsWafCaptcha.renderCaptcha(captchaDiv.current!, {
              apiKey: "...API key goes here...",
              onSuccess: async _wafToken => {
                const response = await window.AwsWafIntegration.fetch('/your/api/url');
    
                if (response.status !== 200) {
                  setData({ state: "error", message: "Unable to load data." });
                }
    
                const data = await response.json();
                setData({ state: "loaded", data });
              },
              onError: e => {
                console.error(e);
                setData({ state: "error", message: "Unable to load data." });
              }
              /* ...other configuration parameters as needed... */
          });
          

          return;
        }

        if (response.status !== 200) {
          throw new Error(`Unexpected response status: ${response.status}`);
        }

        const data = await response.json();
        setData({ state: "loaded", data });
      } catch (e) {
        console.error(e);
        setData({ state: "error", message: "Unable to load data." });
      }
    })();
  }, []);

  return (
    <div>
      <div ref={captchaDiv} />
      <div>
        {/* render the data */}
      </div>
    </div>
  );
}

Preventing CAPTCHA token reuse

Although AWS WAF provides built-in CAPTCHA functionality, additional security measures are necessary to prevent token reuse events. In these events, threat actors can solve a CAPTCHA one time and distribute the token across their botnet. AWS WAF Bot Control offers protection against this vulnerability by detecting and blocking CAPTCHA token reuse across multiple IPs, ASNs, or countries.

To implement this protection:

  1. Configure the AWSManagedRulesBotControlRuleSet managed rule group after your rate-limiting rules.
  2. Use the targeted protection level.
  3. Apply Count or Allow actions to specific rules that you don’t want to apply to your traffic instead of a Block or CAPTCHA action.
  4. Monitor and adjust rule actions based on observed traffic patterns.

Conclusion

In this post, you learned how we implemented comprehensive DDoS protection using AWS WAF by:

  • Implementing best practices for AWS WAF network topology using CloudFront
  • Segmenting human and machine traffic in our AWS WAF configuration
  • Using tiered rate limits and CAPTCHA to allow legitimate requests
  • Preventing CAPTCHA token reuse by using AWS WAF Bot Control

To learn more about fine-tuning and optimizing AWS WAF Bot Control, refer to Fine-tune and optimize AWS WAF Bot Control mitigation capability by Dmitriy Novikov in the AWS Security Blog.


About the authors

Realizing ocean data democratization: Furuno Electric’s initiatives using Amazon DataZone

Post Syndicated from Akira Mikami original https://aws.amazon.com/blogs/big-data/realizing-ocean-data-democratization-furuno-electrics-initiatives-using-amazon-datazone/

This is a guest post authored by Akira Mikami, a technical expert at Furuno Electric. The content and opinions in this post are those of the third-party author and AWS is not responsible for the content or accuracy of this post.

Since successfully commercializing the world’s first fish finder in 1948, Furuno Electric has been developing unique ultrasonic and electronic technologies in the marine electronics field. Under the company motto of “making the invisible visible”, they’ve have expanded their business centered on marine sensing technology and are now extending into subscription-based data businesses using Internet of Things (IoT) data. They’re are actively promoting the planning and development of data businesses to realize their new management vision outlined in FURUNO GLOBAL VISION NAVI NEXT 2030.

Like many manufacturing companies, Furuno Electric faced significant changes in revenue structure and technical architecture as they transitioned from traditional business to data-driven business. To succeed in this transformation, it was essential to build a foundation that promotes data utilization across the entire organization.

This post demonstrates how Furuno Electric built their system using Amazon DataZone and other Amazon Web Services (AWS) services to address technical infrastructure fragmentation, establish proper security governance, and develop an effective data business promotion system as part of their journey transitioning from a traditional manufacturing company to a data-driven business.

Challenges

Furuno Electric faced three specific challenges in promoting their data business: technical infrastructure fragmentation and duplication, lack of security governance, and underdeveloped data business promotion system.

Project managers in the data business were independently designing and building data infrastructure, resulting in duplication of components for data collection, processing, and storage. This situation created wasteful development investments, hindered effective use of common data, and caused inefficient states that took time to launch businesses. Marine data services including fishing vessel data collection and sharing system, FWC, and Furuno Open Platform (FOP) had similar functions implemented separately for each project along the functional axes of data collection, processing, visualization, and analysis, resulting in unnecessary workload across the organization.

Security measures were considered and implemented separately by each department, and although checklists existed, they weren’t applied uniformly. This resulted in a lack of consistency in security measures, duplicate consideration costs for each department, and uncertainty in the comprehensiveness of measures. Integrated risk management was also difficult.

The organizational structure wasn’t prepared for the iterative development processes and long-term revenue models specific to data businesses, and there was a lack of mechanisms for cross-departmental data utilization and joint development. The distributed operational structure across departments made it difficult to rapidly deploy and continuously improve data businesses. In the process of creating data businesses, it became necessary to build entirely different customer relationships compared to traditional product sales businesses. In terms of organizational management and talent strategy, there was a need to transition from a top-down, risk-averse, specialized skill-focused structure to a bottom-up, challenge-oriented structure that emphasizes communication skills and diversity.

Solution overview

Furuno Electric built a data management foundation centered on Amazon DataZone, Amazon Simple Storage Service (Amazon S3), AWS Glue, and AWS Control Tower, a comprehensive solution designed to address each of the three challenges mentioned in the preceding section.

Building the integrated data platform JuBuRaw

To address technical infrastructure fragmentation and duplication, they built Junction Architecture of Business Raw Data (JuBuRaw), a platform that consolidates common components for data collection, storage, management, and authentication. Using AWS Cloud Development Kit (AWS CDK) to code the infrastructure, they achieved standardization and automation of environment construction. This provides consistency and reproducibility, making it easier to add new systems and migrate existing systems to the common platform. Merely by executing CDK, a standard data pipeline (using AWS IoT Core, Amazon S3, AWS Glue, Amazon Kinesis, Amazon API Gateway, and AWS Lambda) for a specific system is automatically built. This eliminates duplicate design and development within the organization, reducing business launch time and improving fixed cost management. By standardizing common functions, they reduced the management and operation costs of existing systems and enabled the launch of new systems in half the time compared to before.

The following diagram is the overall JuBuRaw architecture.

Security control with AWS Control Tower

To address the lack of security governance, they implemented a comprehensive security framework centered on AWS Control Tower to apply consistent security policies across multiple accounts. With automated monitoring systems using AWS Security Hub, AWS Config, and AWS CloudTrail and an integrated authentication system using AWS IAM Identity Center, they provide security consistency while reducing operational costs and management burden.

With the organization’s management account at the top, they placed AWS Control Tower, AWS Organizations, and AWS IAM Identity Center to achieve hierarchical security management. By adopting a multi-layered defense structure consisting of account baselines with AWS CloudTrail and AWS Config enabled, log archive environments, and audit and security operation environments, consistent security policies are applied to all accounts, enabling early detection and response to security incidents. This integrated approach has reduced the workload for security responses. This configuration is shown in the following diagram.

Establishing a data democratization foundation with Amazon DataZone

To address the underdeveloped data business promotion system, they introduced Amazon DataZone to streamline data discovery, sharing, and governance across the organization. They clarified the role division between the infrastructure management team and the data management team, centralizing data security policies, quality management, and metadata standardization. With a project-based collaboration environment, they promoted cross-departmental data utilization, establishing a foundation to support the creation and continuous monetization of data businesses.

Organizational reform and operational structure establishment

In parallel with the introduction of technical solutions, they implemented organizational reforms to support medium- to long-term data utilization. The new organizational structure consists of three main roles: the infrastructure management team, the data management team, and the chief data officer. The following chart shows this organizational structure.

The infrastructure management team is responsible for maintaining and developing the technical foundation of the platform, managing multiple accounts using AWS Control Tower, applying and monitoring security baselines, and tracking infrastructure version management and changing history. By specializing in common technologies, they can provide a stable platform.

The data management team is responsible for data quality management and continual improvement using AWS Glue Data Quality, standardization and maintenance of metadata, definition and application of data security policies, management of Amazon DataZone data Catalog, and providing data governance using Amazon DataZone. To maximize the value of data, they focus on deeply understanding business requirements and data characteristics and performing appropriate data management.

The chief data officer is responsible for formulating data business strategies and determining direction, promoting coordination and collaboration between teams, making decisions regarding the evolution of the data management foundation, and fostering a data utilization culture throughout the organization. From a strategic perspective, they oversee the whole and bridge business goals and technology.

This clear division of roles has established an operational structure for effective data utilization, accelerating the data business creation process. Additionally, clarifying data ownership has improved data quality and reliability, promoting data utilization across the organization. This structure is sustainable and can flexibly respond to technological changes and changes in the business environment.

Benefits of the modernized platform

As a concrete application example of the integrated data platform JuBuRaw and organizational structure explained in the previous section, we introduce the migration project of the existing service SHIPS. This use case is a comprehensive migration case that uses all three solution elements of data collection, management, and utilization mentioned earlier.

Furuno Electric provides a system called SHIPS that plots ship position information and monitors the status of equipment installed on ships. By migrating this existing service to the JuBuRaw foundation, the several functional enhancements are expected.

In terms of data integration enhancement, by using the data catalog function of Amazon DataZone, it becomes easier to integrate not only ship position information but also various data sources such as internal systems, IoT devices, other company systems, automatic identification system (AIS) data, and weather and sea condition data. This enables swift data analysis and comprehensive ship management, which means operators can detect potential issues and implement preventive measures before they develop into serious problems. Particularly important is that by storing this data in a common data lake and retaining them as master data, they create an environment where the data can be easily used by other applications.

For security enhancement, organizations can use Amazon DataZone federated governance with publish-subscribe (pubsub) workflow mechanism and fine-grained access control capabilities. This means they can implement detailed permissions management specifically for data assets, rows, and columns while maintaining unified access control and data governance across multiple AWS accounts and organizational boundaries.

In this case, by using the new integrated data management foundation, it becomes possible to integrate individually designed and built data foundations, improving both efficiency and functionality. A consistent data flow from data sources to the data platform and then to individual applications is realized, enabling flexible data utilization centered on the data lake. Linkage with each application can also be easily realized from the data lake, providing expandability for future data utilization.

This SHIPS migration case is a comprehensive approach using the solution elements of the JuBuRaw foundation and is expected to serve as a reference model for future system migrations. It’s expected to achieve both service quality improvement and operational cost reduction.

Future vision and next steps

Based on the data management foundation they’ve built, Furuno Electric aims to further expand and deepen data utilization. As part of their plan to continue and expand digital transformation, they’re currently starting with the migration of SHIPS, but plan to gradually migrate other IoT-related services (such as FOP, FWC, and Ichidake) to the new data management foundation in the future. This is expected to further strengthen the foundation for company-wide data utilization and enhance synergies between services.

Continuous enhancement of secure data sharing and access control is also essential. With the increase in data and expansion of utilization scope, the importance of security and access control will further increase. They’ll optimize the balance between data protection and utilization while incorporating practices accumulated through operations.

Additionally, Furuno Electric is exploring the expansion of their data management capabilities to Amazon SageMaker, specifically using Amazon SageMaker Catalog integrated with Amazon DataZone. This integration will enable them to seamlessly extend their existing data analytics governance workflows into artificial intelligence and machine learning (AI/ML) workloads. By applying the same data discovery, data sharing, and access control foundation across both data analytics and AI model development, they can accelerate the development of new AI-powered services. The unified governance framework will also provide secure and efficient AI adoption throughout the organization.

Through these initiatives, Furuno Electric is realizing their company motto of “making the invisible visible” in the field of data business as well. The integrated data platform JuBuRaw isn’t just an integration of technical foundations but serves as a foundation to support organizational culture transformation and the creation of new business models. As seen in the SHIPS migration case, using this foundation not only enhances existing services but also expands possibilities for new data utilization.

Through building a data foundation that can flexibly respond to business growth and changes while using a cloud-based environment, Furuno Electric has successfully led their digital transformation. They’ll continue to provide new value to customers through the democratization of marine data and accelerate the transition to data-driven business.

This case serves as a reference for many manufacturing companies promoting data utilization, showing that approaches from both technical and organizational perspectives are key to success. As Furuno Electric’s initiatives demonstrate, data democratization and effective utilization play an important role in the digital transformation of manufacturing.


About the Authors

Akira Mikami is a technical expert who played a central role in the FURUNO Data Platform (JuBuRaw) Construction Project at Furuno Electric Co., Ltd. Specializing in data platform construction and architecture, he led the implementation of cloud solutions utilizing AWS. He contributed to achieving efficient data management and strengthening team collaboration, leading the project to success.

Junpei Ozono is a Sr. Go-to-market (GTM) Data & AI solutions architect at Amazon Web Services (AWS) in Japan. He drives technical market creation for data and AI solutions while collaborating with global teams to develop scalable GTM motions. He guides organizations in designing and implementing innovative data-driven architectures powered by AWS services, helping customers accelerate their cloud transformation journey through modern data and AI solutions. His expertise spans across modern data architectures including data mesh, data lakehouse, and generative AI, so customers can build scalable and innovative solutions on Amazon Web Services (AWS).

Mitsuhiko Nishida is an Enterprise Solutions Architecture Automotive & Manufacturing Group Solutions Architect at Amazon Web Services (AWS) in Japan. He serves as a field Solutions Architect for manufacturing customers, helping them solve their business challenges. With expertise in generative AI and manufacturing IT, he guides the design and implementation of innovative solutions leveraging cutting-edge technologies. He supports manufacturing customers in building efficient architecture powered by AWS services to accelerate their cloud transformation journey and contribute to their digital transformation initiatives.

Kaltura reduces observability operational costs by 60% with Amazon OpenSearch Service

Post Syndicated from Ido Ziv original https://aws.amazon.com/blogs/big-data/kaltura-reduces-observability-operational-costs-by-60-with-amazon-opensearch-service/

This post is co-written with Ido Ziv from Kaltura.

As organizations grow, managing observability across multiple teams and applications becomes increasingly complex. Logs, metrics, and traces generate vast amounts of data, making it challenging to maintain performance, reliability, and cost-efficiency.

At Kaltura, an AI-infused video-first company serving millions of users across hundreds of applications, observability is mission-critical. Understanding system behavior at scale isn’t just about troubleshooting—it’s about providing seamless experiences for customers and employees alike. But achieving effective observability at this scale comes with challenges: managing spans; correlating logs, traces, and events across distributed systems; and maintaining visibility without overwhelming teams with noise. Balancing granularity, cost, and actionable insights requires constant tuning and thoughtful architecture.

In this post, we share how Kaltura transformed its observability strategy and technological stack by migrating from a software as a service (SaaS) logging solution to Amazon OpenSearch Service—achieving higher log retention, a 60% reduction in cost, and a centralized platform that empowers multiple teams with real-time insights.

Observability challenges at scale

Kaltura ingests over 8TB of logs and traces daily, processing more than 20 billion events across 6 production AWS Regions and over 200 applications—with log spikes reaching up to 6 GB per second. This immense data volume, combined with a highly distributed architecture, created significant challenges in observability. Historically, Kaltura relied on a SaaS-based observability solution that met initial requirements but became increasingly difficult to scale. As the platform evolved, teams generated disparate log formats, applied retention policies that no longer reflected data value, and operated more than 10 organically grown observability sources. The lack of standardization and visibility required extensive manual effort to correlate data, maintain pipelines, and troubleshoot issues – leading to rising operational complexity and fixed costs that didn’t scale efficiently with usage.

Kaltura’s DevOps team recognized the need to reassess their observability solution and began exploring a variety of options, from self-managed platforms to fully managed SaaS offerings. After a comprehensive evaluation, they made the strategic decision to migrate to OpenSearch Service, using its advanced features such as Amazon OpenSearch Ingestion, the Observability plugin, UltraWarm storage, and Index State Management.

Solution overview

Kaltura created a new AWS account that would be a dedicated observability account, where OpenSearch Service was deployed. Logs and traces were collected from different accounts and producers such as microservices on Amazon Elastic Kubernetes Service (Amazon EKS) and services running on Amazon Elastic Compute Cloud (Amazon EC2).

By using AWS services such as AWS Identity and Access Management (IAM), AWS Key Management Service (AWS KMS), and Amazon CloudWatch, Kaltura was able to meet the standards to create a production-grade system while keeping security and reliability in mind. The following figure shows a high-level design of the environment setup.

Ingestion

As seen in the following diagram, logs are shipped using log shippers, also known as collectors. In Kaltura’s case, they used Fluent Bit. A log shipper is a tool designed to collect, process, and transport log data from various sources to a centralized location, such as log analytics platforms, management systems, or an aggregator system. Fluent Bit was used in all sources and also provided light processing abilities. Fluent Bit was deployed as a daemonset in Kubernetes. The application development teams didn’t change their code, because the Fluent Bit pods were reading the stdout of the application pods.

The following code is an example of FluentBit configurations for Amazon EKS:

[INPUT]
   Name                tail
   Path                /var/log/containers/*.log
   Tag                 kube.*
   Skip_Long_Lines     On
   multiline.parser    docker, cri
[FILTER]
   alias               k8s
   # kubernetes filter to parse all logs
   Name                kubernetes
   Match               kube.*
   Kube_Tag_Prefix     kube.var.log.containers.
   Annotations         On
   Labels              Off
   Merge_Log           On
   Keep_Log            Off
   Kube_URL            https://kubernetes.default.svc.cluster.local:443 
[FILTER]
   alias               apps
   Name                rewrite_tag
   Match               kube.*
   Rule                $kubernetes['annotations']['kaltura.com/observability'] ^apps$ 
[OUTPUT]
   Name                http
   Match               apps.*
   Alias               apps
   Host                xxxxx.us-east-1.osis.amazonaws.com
   Port                443
   URI                 /log/apps
   Format              json
   aws_auth            true
   aws_region          us-east-1
   aws_service         osis
   aws_role_arn        arn:aws:iam::xxxxx:role/osis-ingestion-role
   Log_Level           trace
   tls On

Spans and traces were collected directly from the application layer using a seamless integration approach. To facilitate this, Kaltura deployed an OpenTelemetry Collector (OTEL) using the OpenTelemetry Operator for Kubernetes. Additionally, the team developed a custom OTEL code library, which was incorporated into the application code to efficiently capture and log traces and spans, providing comprehensive observability across their system.

Data from Fluent Bit and OpenTelemetry Collector was sent to OpenSearch Ingestion, a fully managed, serverless data collector that delivers real-time log, metric, and trace data to OpenSearch Service domains and Amazon OpenSearch Serverless collections. Each producer sent data to a specific pipeline, one for logs and one for traces, where data was transformed, aggregated, enriched, and normalized before being sent to OpenSearch Service. The trace pipeline used the otel_trace and service_map processors, while using the OpenSearch Ingestion OpenTelemetry trace analytics blueprint.

The following code is an example of the OpenSearch Ingestion pipeline for logs:

version: "2"
entry-pipeline:
 source:
   http:
     path: "/log/apps"

 processor:
   - add_entries:
       entries:
       - key: "log_type"
         value: "default"
       - key: "log_type"
         value: "api"
         add_when: 'contains(/filename, "api.log")'
         overwrite_if_key_exists: true
       - key: "log_type"
         value: "stats"
         add_when: 'contains(/filename, "stats.log")'
         overwrite_if_key_exists: true
       - key: "log_type"
         value: "event"
         add_when: 'contains(/filename, "event.log")'
         overwrite_if_key_exists: true
       - key: "log_type"
         value: "login"
         add_when: 'contains(/filename, "login.log")'
         overwrite_if_key_exists: true

   - grok:
       grok_when: '/log_type == "api"'
       match:
         log: ['^\[%%{DATA:timestamp}] \[%%{DATA:logIp}\] \[%%{DATA:host}\] \[%%{WORD:id}\] %%{WORD:priorityName}\(%%{NUMBER:priority}\): \[memory: %%{DATA:memory} MB, real: %%{DATA:real}MB\] %%{GREEDYDATA:message}']

   - date:
       match:
         - key: timestamp
           patterns: ["dd-MMM-yyyy HH:mm:ss", "dd/MMM/yyyy:HH:mm:ss Z", "EEE MMM dd HH:mm:ss.SSSSSS yyyy"]

       destination: "@timestamp"
       output_format: "yyyy-MM-dd'T'HH:mm:ss"

   - rename_keys:
       entries:
       - from_key: "timestamp"
         to_key: "@timestamp"
         overwrite_if_to_key_exists: false
       - from_key: "date"
         to_key: "@timestamp"
         overwrite_if_to_key_exists: false

   - drop_events:
       drop_when: 'contains(/filename, "simplesamlphp.log")'


 sink:
   - opensearch:
       hosts: ["${opensearch_host}"]
       index: '$${/env}-api-$${/log_type}-app-logs'
       index_type: custom
       action: create
       bulk_size: 20
       aws:
         sts_role_arn: ${sts_role_arn}
         region:  ${region}
       dlq:
         s3:
           bucket: "${bucket}"
           key_path_prefix: 'my-app-dlq-files'
           region: "${region}"
           sts_role_arn: "${sts_role_arn}"

The preceding example shows the use of processors such as grok, date, add_entries, rename_keys, and drop_events:

  • add_entries:
    • Adds a new field log_type based on filename
    • Default: “default”
    • If the filename contains specific substrings (such as api.log or stats.log), it assigns a more specific type
  • grok:
    • Applies Grok parsing to logs of type “api”
    • Extracts fields like timestamp, logIp, host, priorityName, priority, memory, real, and message using a custom pattern
  • date:
    • Parses timestamp strings into a standard datetime format
    • Stores it in a field called @timestamp based on ISO8601 format
    • Handles multiple timestamp patterns
  • rename_keys:
    • timestamp or date are renamed into @timestamp
    • Does not overwrite if @timestamp already exists
  • drop_events:
    • Drops logs where filename contains simplesamlphp.log
    • This is a filtering rule to ignore noisy or irrelevant logs

The following is an example of the input of a log line:

   "log": "[25-Mar-2025 18:23:18] [127.0.0.1] [the-most-awesome-server-in-kaltura] [67e2f496cc321] INFO(6): [memory: 4.51 MB, real: 6MB] [request: 1] [time: 0.0263s / total: 0.0263s]",

After processing, we get the following code:

    "log_type": "api",
    "priorityName": "INFO",
    "memory": "4.51",
    "host": "the-most-awesome-server-in-kaltura",
    "real": "6",
    "priority": "6",
    "message": "[request: 1] [time: 0.0263s / total: 0.0263s]",
    "logIp": "127.0.0.1",
    "id": "67e2f496cc321",
    "@timestamp": "2025-03-25T18:23:18"

Kaltura followed some OpenSearch Ingestion best practices, such as:

  • Including a dead-letter queue (DLQ) in pipeline configuration. This can significantly help troubleshoot pipeline issues.
  • Starting and stopping pipelines to optimize cost-efficiency, when possible.
  • During the proof of concept stage:
    • Installing Data Prepper locally for faster development iterations.
    • Disabling persistent buffering to expedite blue-green deployments.

Achieving operational excellence with efficient log and trace management

Logs and traces play a vital role in identifying operational issues, but they come with unique challenges. First, they represent time series data, which inherently evolves over time. Second, their value typically diminishes as time passes, making efficient management crucial. Third, they are append-only in nature. With OpenSearch, Kaltura faced distinct trade-offs between cost, data retention, and latency. The goal was to make sure valuable data remained accessible to engineering teams with minimal latency, but the solution also needed to be cost-effective. Balancing these factors required thoughtful planning and optimization.

Data was ingested to OpenSearch data streams, which simplifies the process of ingesting append-only time series data. Several Index State Management (ISM) policies were applied to different data streams, which were dependent on log retention requirements. ISM policies handled moving indexes from hot storage to UltraWarm, and eventually deleting the indexes. This allowed a customizable and cost-effective solution, with low latency for querying new data and reasonable latency for querying historical data.

The following example ISM policy makes sure indexes are managed efficiently, rolled over, and moved to different storage tiers based on their age and size, and eventually deleted after 60 days. If an action fails, it is retried with an exponential backoff strategy. In case of failures, notifications are sent to relevant teams to keep them informed.

{
    "id": "retention",
    "policy": {
        "description": "production ISM",
        },
        "default_state": "hot",
        "states": [
            {
                "name": "hot",
                "actions": [
                    {
                        "retry": {
                            "count": 5,
                            "backoff": "exponential",
                            "delay": "1h"
                        },
                        "rollover": {
                            "min_primary_shard_size": "30gb",
                            "copy_alias": false
                        }
                    }
                ],
                "transitions": [
                    {
                        "state_name": "warm",
                        "conditions": {
                            "min_index_age": "2d"
                        }
                    }
                ]
            },
            {
                "name": "warm",
                "actions": [
                    {
                        "retry": {
                            "count": 5,
                            "backoff": "exponential",
                            "delay": "1h"
                        },
                        "warm_migration": {}
                    }
                ],
                "transitions": [
                    {
                        "state_name": "cold",
                        "conditions": {
                            "min_index_age": "14d"
                        }
                    }
                ]
            },
            {
                "name": "cold",
                "actions": [
                    {
                        "retry": {
                            "count": 5,
                            "backoff": "exponential",
                            "delay": "1h"
                        },
                        "cold_migration": {
                            "start_time": null,
                            "end_time": null,
                            "timestamp_field": "@timestamp",
                            "ignore": "none"
                        }
                    }
                ],
                "transitions": [
                    {
                        "state_name": "delete",
                        "conditions": {
                            "min_index_age": "60d"
                        }
                    }
                ]
            },
            {
                "name": "delete",
                "actions": [
                    {
                        "retry": {
                            "count": 3,
                            "backoff": "exponential",
                            "delay": "1m"
                        },
                        "cold_delete": {}
                    }
                ],
                "transitions": []
            }
        ],
        "ism_template": [
            {
                "index_patterns": [
                    "*-logs"
                ],
                "priority": 50,
            }
        ]
    }
}

To create a data stream in OpenSearch, a definition of index template is required, which configures how the data stream and its backing indexes will behave. In the following example, the index template specifies key index settings such as the number of shards, replication, and refresh interval—controlling how data is distributed, replicated, and refreshed across the cluster. It also defines the mappings, which describe the structure of the data—what fields exist, their types, and how they should be indexed. These mappings make sure the data stream knows how to interpret and store incoming log data efficiently. Finally, the template enables the @timestamp field as the time-based field required for a data stream.

{
  "index_patterns": [
    "*my-app-logs"
  ],
  "template": {
    "settings": {
      "index.number_of_shards": "32",
      "index.number_of_replicas": "0",
      "index.refresh_interval": "60s"
    },
    "mappings": {
      "properties": {
        "priorityName": {
          "type": "keyword"
        },
        "log_type": {
          "type": "keyword"
        },
        "@timestamp": {
          "type": "date"
        },
        "memory": {
          "type": "float"
        },
        "host": {
          "type": "keyword"
        },
        "pid": {
          "type": "keyword"
        },
        "real": {
          "type": "float"
        },
        "env": {
          "type": "keyword"
        },
        "message": {
          "type": "text"
        },
        "priority": {
          "type": "integer"
        },
        "logIp": {
          "type": "ip"
        }
      }
    }
  },
  "composed_of": [],
  "priority": "100",
  "_meta": {
    "flow": "simple"
  },
  "data_stream": {
    "timestamp_field": {
      "name": "@timestamp"
    }
  },
  "name": "my-app-logs"
}

Implementing role-based access control and user access

The new observability platform is accessed by many types of users; internal users log in to OpenSearch Dashboards using SAML-based federation with Okta. The following diagram illustrates the user flow.

Each user accesses the dashboards to view observability items relevant to their role. Fine-grained access control (FGAC) is enforced in OpenSearch using built-in IAM role and SAML group mappings to implement role-based access control (RBAC).When users log in to the OpenSearch domain, they are automatically routed to the appropriate tenant based on their assigned role. This setup makes sure developers can create dashboards tailored to debugging within development environments, and support teams can build dashboards focused on identifying and troubleshooting production issues. The SAML integration alleviates the need to manage internal OpenSearch users entirely.

For each role in Kaltura, a corresponding OpenSearch role was created with only the necessary permissions. For instance, support engineers are granted access to the monitoring plugin to create alerts based on logs, whereas QA engineers, who don’t require this functionality, are not granted that access.

The following screenshot shows the role of the DevOps engineers defined with cluster permissions.

These users are routed to their own dedicated DevOps tenant, to which they only have write access. This makes it possible for different users from different roles in Kaltura to create the dashboard items that focus on their priorities and needs. OpenSearch supports backend role mapping; Kaltura mapped the Okta group to the role so when a user logs in from Okta, they automatically get assigned based on their role.

This also works with IAM roles to facilitate automations in the cluster using external services, such as OpenSearch Ingestion pipelines, as can be seen in the following screenshot.

Using observability features and service mapping for enhanced trace and log correlation

After a user is logged in, they can use the Observability plugins, view surrounding events in logs, correlate logs and traces, and use the Trace Analytics plugin. Users can inspect traces and spans, and group traces with latency information using built-in dashboards. Users can also drill down to a specific trace or span and correlate it back to log events. The service_map processor used in OpenSearch Ingestion sends OpenTelemetry data to create a distributed service map for visualization in OpenSearch Dashboards.

Using the combined signals of traces and spans, OpenSearch discovers the application connectivity and maps them to a service map.

After OpenSearch ingests the traces and spans from Otel, they are aggregated to groups according to paths and trends. Durations are also calculated and presented to the user over time.

With a trace ID, it’s possible to filter out all the relevant spans by the service and see how long each took, identifying issues with external services such as MongoDB and Redis.

From the spans, users can discover the relevant logs.

Post-migration enhancements

After the migration, a strong developer community emerged within Kaltura that embraced the new observability solution. As adoption grew, so did requests for new features and enhancements aimed at improving the overall developer experience.

One key improvement was extending log retention. Kaltura achieved this by re-ingesting historical logs from Amazon Simple Storage Service (Amazon S3) using a dedicated OpenSearch Ingestion pipeline with Amazon S3 read permissions. With this enhancement, teams can access and analyze logs from up to a year ago using the same familiar dashboards and filters.

In addition to monitoring EKS clusters and EC2 instances, Kaltura expanded its observability stack by integrating more AWS services. Amazon API Gateway and AWS Lambda were introduced to support log ingestion from external vendors, allowing for seamless correlation with existing data and broader visibility across systems.

Finally, to empower teams and promote autonomy, data stream templates and ISM policies are managed directly by developers within their own repositories. By using infrastructure as code tools like Terraform, developers can define index mappings, alerts, and dashboards as code—versioned in Git and deployed consistently across environments.

Conclusion

Kaltura successfully implemented a smart log retention strategy, extending real time retention from 5 days for all log types to 30 days for critical logs, while maintaining cost-efficiency through the use of UltraWarm nodes. This approach led to a 60% reduction in costs compared to their previous solution. Additionally, Kaltura consolidated their observability platform, streamlining operations by merging 10 separate systems into a unified, all-in-one solution. This consolidation not only improved operational efficiency but also sparked increased engagement from developer teams, driving feature requests, fostering internal design collaborations, and attracting early adopters for new enhancements. If Kaltura’s journey has inspired you and you’re thinking about implementing a similar solution in your organization, consider these steps:


About the authors

Ido Ziv is a DevOps team leader in Kaltura with over 6 years of experience. His hobbies include sailing and Kubernetes (but not at the same time).

Roi Gamliel is a Senior Solutions Architect helping startups build on AWS. He is passionate about the OpenSearch Project, helping customers fine-tune their workloads and maximize results.

Yonatan Dolan is a Principal Analytics Specialist at Amazon Web Services. He is located in Israel and helps customers harness AWS analytical services to use data, gain insights, and derive value.

How Skroutz handles real-time schema evolution in Amazon Redshift with Debezium

Post Syndicated from Konstantina Mavrodimitraki original https://aws.amazon.com/blogs/big-data/how-skroutz-handles-real-time-schema-evolution-in-amazon-redshift-with-debezium/

This guest post was co-authored with Kostas Diamantis from Skroutz.

At Skroutz, we are passionate about our product, and it is always our top priority. We are constantly working to improve and evolve it, supported by a large and talented team of software engineers. Our product’s continuous innovation and evolution lead to frequent updates, often necessitating changes and additions to the schemas of our operational databases.

When we decided to build our own data platform to meet our data needs, such as supporting reporting, business intelligence (BI), and decision-making, the main challenge—and also a strict requirement—was to make sure it wouldn’t block or delay our product development.

We chose Amazon Redshift to promote data democratization, empowering teams across the organization with seamless access to data, enabling faster insights and more informed decision-making. This choice supports a culture of transparency and collaboration, as data becomes readily available for analysis and innovation across all departments.

However, keeping up with schema changes from our operational databases, while updating the data warehouse without constantly coordinating with development teams, delaying releases, or risking data loss, became a new challenge for us.

In this post, we share how we handled real-time schema evolution in Amazon Redshift with Debezium.

Solution overview

Most of our data resides in our operational databases, such as MariaDB and MongoDB. Our approach involves using the change data capture (CDC) technique, which automatically handles the schema evolution of the data stores being captured. For this, we used Debezium along with a Kafka cluster. This solution enables schema changes to be propagated without disrupting the Kafka consumers.

However, handling schema evolution in Amazon Redshift became a bottleneck, prompting us to develop a strategy to address this challenge. It’s important to note that, in our case, changes in our operational databases primarily involve adding new columns rather than breaking changes like altering data types. Therefore, we have implemented a semi-manual process to resolve this issue, along with a mandatory alerting mechanism to notify us of any schema changes. This two-step process consists of handling schema evolution in real time and handling data updates in an asynchronous manual step. The following architectural diagram illustrates a hybrid deployment model, integrating both on-premises and cloud-based components.

End-to-end data migration workflow from on-premises databases to AWS cloud using CDC, messaging, and data warehouse services

The data flow begins with data from MariaDB and MongoDB, captured using Debezium for CDC in near real-time mode. The captured data is streamed to a Kafka cluster, where Kafka consumers (built on the Ruby Karafka framework) read and write them to the staging area, either in Amazon Redshift or Amazon Simple Storage Service (Amazon S3). From the staging area, DataLoaders promote the data to production tables in Amazon Redshift. At this stage, we apply the slowly changing dimension (SCD) concept to these tables, using Type 7 for most of them.

In data warehousing, an SCD is a dimension that stores data, and though it’s generally stable, it might change over time. Various methodologies address the complexities of SCD management. SCD Type 7 places both the surrogate key and the natural key into the fact table. This allows the user to select the appropriate dimension records based on:

  • The primary effective date on the fact record
  • The most recent or current information
  • Other dates associated with the fact record

Afterwards, analytical jobs are run to create reporting tables, enabling BI and reporting processes. The following diagram provides an example of the data modeling process from a staging table to a production table.

Database schema evolution: staging.shops to production.shops with added temporal and versioning columns

The architecture depicted in the diagram shows only our CDC pipeline, which fetches data from our operational databases and doesn’t include other pipelines, such as those for fetching data through APIs, scheduled batch processes, and many more. Also note that our convention is that dw_* columns are used to catch SCD metadata information and other metadata in general. In the following sections, we discuss the key components of the solution in more detail.

Real-time workflow

For the schema evolution part, we focus on the column dw_md_missing_data, which captures schema evolution changes in near real time that occur in the source databases. When a new change is produced to the Kafka cluster, the Kafka consumer is responsible for writing this change to the staging table in Amazon Redshift. For example, a message produced by Debezium to the Kafka cluster will have the following structure when a new shop entity is created:

{
  "before": null,
  "after": {
    "id": 1,
    "name": "shop1",
    "state": "hidden"
  },
  "source": {
    ...
    "ts_ms": "1704114000000",
    ...
  },
  "op": "c",
  ...
}

The Kafka consumer is responsible for preparing and executing the SQL INSERT statement:

INSERT INTO staging.shops (
  id,
  "name",
  state,
  dw_md_changed_at,
  dw_md_operation,
  dw_md_missing_data
)
VALUES
  (
    1,
    'shop1',
    'hidden',
    '2024-01-01 13:00:00',
    'create',
    NULL
  )
;

After that, let’s say a new column is added to the source table called new_column, with the value new_value.
The new message produced to the Kafka cluster will have the following format:

{
  "before": { ... },
  "after": {
    "id": 1,
    "name": "shop1",
    "state": "hidden",
    "new_column": "new_value"
  },
  "source": {
    ...
    "ts_ms": "1704121200000"
    ...
  },
  "op": "u"
  ...
}

Now the SQL INSERT statement executed by the Kafka consumer will be as follows:

INSERT INTO staging.shops (
  id,
  "name",
  state,
  dw_md_changed_at,
  dw_md_operation,
  dw_md_missing_data
)
VALUES
  (
    1,
    'shop1',
    'hidden',
    '2024-01-01 15:00:00',
    'update',
    JSON_PARSE('{"new_column": "new_value"}') /* <-- check this */
  )
;

The consumer performs an INSERT as it would for the known schema, and anything new is added to the dw_md_missing_data column as key-value JSON. After the data is promoted from the staging table to the production table, it will have the following structure.

Production.shops table displaying temporal data versioning with creation, update history, and current state indicators

At this point, the data flow continues running without any data loss or the need for communication with teams responsible for maintaining the schema in the operational databases. However, this data might not be easily accessible for the data consumers, analysts, or other personas. It’s worth noting that dw_md_missing_data is defined as a column of the SUPER data type, which was introduced in Amazon Redshift to store semistructured data or documents as values.

Monitoring mechanism

To track new columns added to a table, we have a scheduled process that runs weekly. This process checks for tables in Amazon Redshift with values in the dw_md_missing_data column and generates a list of tables requiring manual action to make this data available through a structured schema. A notification is then sent to the team.

Manual remediation steps

In the aforementioned example, the manual steps to make this column available would be:

  1. Add the new columns to both staging and production tables:
ALTER TABLE staging.shops ADD COLUMN new_column varchar(255);
ALTER TABLE production.shops ADD COLUMN new_column varchar(255);
  1. Update the Kafka consumer’s known schema. In this step, we just need to add the new column name to a simple array list. For example:
class ShopsConsumer < ApplicationConsumer
  SOURCE_COLUMNS = [
    'id',
    'name',
    'state',
    'new_column' # this one is the new column
  ]
 
  def consume
    # Ruby code for:
    #   1. data cleaning
    #   2. data transformation
    #   3. preparation of the SQL INSERT statement
 
    RedshiftClient.conn.exec <<~SQL
      /*
        generated SQL INSERT statement
      */
    SQL
  end
end
  1. Update the DataLoader’s SQL logic for the new column. A DataLoader is responsible for promoting the data from the staging area to the production table.
class DataLoader::ShopsTable < DataLoader::Base
  class << self
    def load
      RedshiftClient.conn.exec <<~SQL
        CREATE TABLE staging.shops_new (LIKE staging.shops);
      SQL
 
      RedshiftClient.conn.exec <<~SQL
        /*
          We move the data to a new table because in staging.shops
          the Kafka consumer will continue add new rows
        */
        ALTER TABLE staging.shops_new APPEND FROM staging.shops;
      SQL
 
      RedshiftClient.conn.exec <<~SQL
        BEGIN;
          /*
            SQL to handle
              * data deduplications etc
              * more transformations
              * all the necessary operations in order to apply the data modeling we need for this table
          */
 
          INSERT INTO production.shops (
            id,
            name,
            state,
            new_column, /* --> this one is the new column <-- */
            dw_start_date,
            dw_end_date,
            dw_current,
            dw_md_changed_at,
            dw_md_operation,
            dw_md_missing_data
          )
          SELECT
            id,
            name,
            state,
            new_column, /* --> this one is the new column <-- */
            /*
              here is the logic to apply the data modeling (type 1,2,3,4...7)
            */
          FROM
            staging.shops_new
          ;
 
          DROP TABLE staging.shops_new;
        END TRANSACTION;
      SQL
    end
  end
end
  1. Transfer the data that has been loaded in the meantime from the dw_md_missing_data SUPER column to the newly added column and then clean up. In this step, we just need to run a data migration like the following:
BEGIN;
 
  /*
    Transfer the data from the `dw_md_missing_data` to the corresponding column
  */
  UPDATE production.shops
  SET new_column = dw_md_missing_data.new_column::varchar(255)
  WHERE dw_md_missing_data.new_column IS NOT NULL;
 
  /*
    Clean up dw_md_missing_data column
  */
  UPDATE production.shops
  SET dw_md_missing_data = NULL
  WHERE dw_md_missing_data IS NOT NULL;
 
END TRANSACTION;

To perform the preceding operations, we make sure that no one else performs changes to the production.shops table because we want no new data to be added to the dw_md_missing_data column.

Conclusion

The solution discussed in this post enabled Skroutz to manage schema evolution in operational databases while seamlessly updating the data warehouse. This alleviated the need for constant development team coordination and removed risks of data loss during releases, ultimately fostering innovation rather than stifling it.

As the migration of Skroutz to the AWS Cloud approaches, discussions are underway on how the current architecture can be adapted to align more closely with AWS-centered principles. To that end, one of the changes being considered is Amazon Redshift streaming ingestion from Amazon Managed Streaming for Apache Kafka (Amazon MSK) or open source Kafka, which will make it possible for Skroutz to process large volumes of streaming data from multiple sources with low latency and high throughput to derive insights in seconds.

If you face similar challenges, discuss with an AWS representative and work backward from your use case to provide the most suitable solution.


About the authors

Konstantina Mavrodimitraki is a Senior Solutions Architect at Amazon Web Services, where she assists customers in designing scalable, robust, and secure systems in global markets. With deep expertise in data strategy, data warehousing, and big data systems, she helps organizations transform their data landscapes. A passionate technologist and people person, Konstantina loves exploring emerging technologies and supports the local tech communities. Additionally, she enjoys reading books and playing with her dog.

Kostas Diamantis is the Head of the Data Warehouse at Skroutz company. With a background in software engineering, he transitioned into data engineering, using his technical expertise to build scalable data solutions. Passionate about data-driven decision-making, he focuses on optimizing data pipelines, enhancing analytics capabilities, and driving business insights.

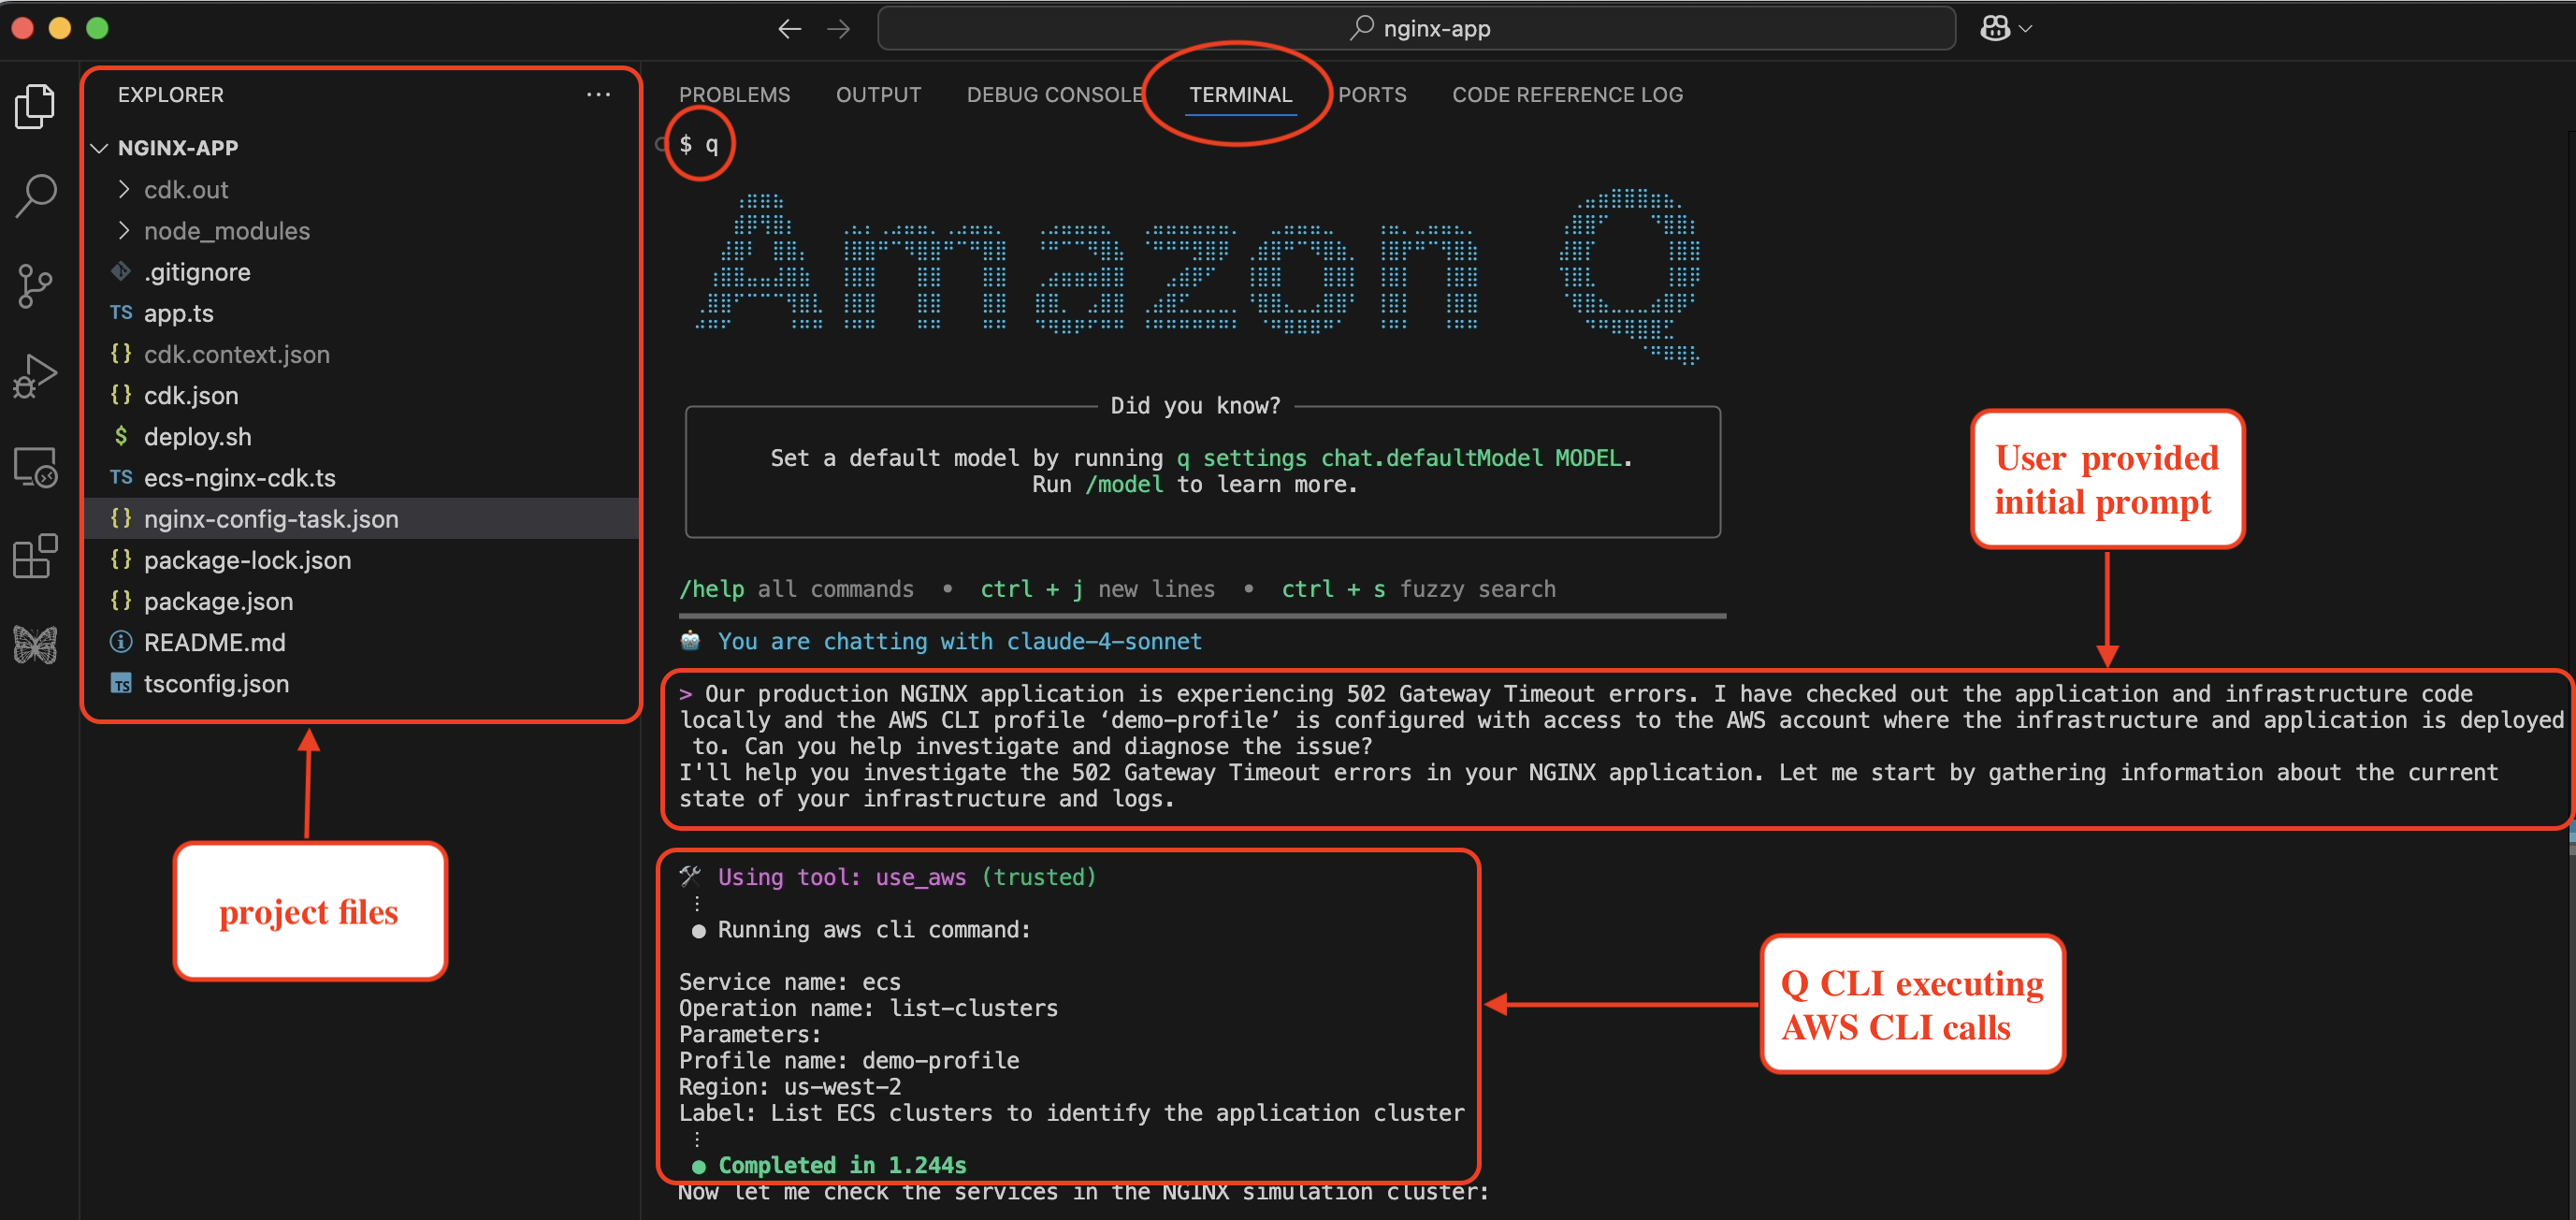
Streamline Operational Troubleshooting with Amazon Q Developer CLI

Post Syndicated from Kirankumar Chandrashekar original https://aws.amazon.com/blogs/devops/streamline-operational-troubleshooting-with-amazon-q-developer-cli/

Amazon Q Developer is the most capable generative AI–powered assistant for software development, helping developers perform complex workflows. Amazon Q Developer command-line interface (CLI) combines conversational AI with direct access to AWS services, helping you understand, build, and operate applications more effectively. The Amazon Q Developer CLI executes commands, analyzes outputs, and provides contextual recommendations based on best practices for troubleshooting tools and platforms available on your local machine.

In today’s cloud-native environments, troubleshooting production issues often involves juggling multiple terminal windows, parsing through extensive log files, and navigating numerous AWS console pages. This constant context-switching delays problem resolution and adds cognitive burden to teams managing cloud infrastructure.

In this blog post, you will explore how Amazon Q Developer CLI transforms the troubleshooting experience by streamlining challenging scenarios through conversational interactions.

The Traditional Troubleshooting Experience

When issues arise, engineers typically spend hours manually examining infrastructure configurations, reviewing logs across services, and analyzing error patterns. The process requires switching between multiple interfaces, correlating information from various sources, and deep AWS knowledge. This complex workflow often extends problem resolution from hours into days and increase the burden on the infrastructure teams.

Solution: Amazon Q Developer CLI

Amazon Q Developer CLI streamlines the entire troubleshooting process, from initial investigation to problem resolution, making complex AWS troubleshooting accessible and efficient through simple conversations.

How Amazon Q Developer CLI works:

  • Natural Language Interface: Execute AWS CLI commands and interact with AWS services using conversational prompts
  • Automated Discovery: Map out infrastructure and analyze configurations
  • Intelligent Log Analysis: Parse, correlate, and analyze logs across services
  • Root Cause Identification: Pinpoint issues through AI-powered reasoning
  • Guided Remediation: Implement fixes with minimal human intervention
  • Validation: Test solutions and explain complex issues simply

One of the built-in tools within the Amazon Q Developer CLI, use_aws, enables natural language interaction with AWS services, as shown in Figure 1. This tool leverages the AWS CLI permissions configured on your local machine, allowing secure and authorized access to your AWS resources.

A command line interface showing a list of tools and their permissions. The display is titled "/tools" and shows several built-in tools including execute_bash, fs_read, fs_write, report_issue, and use_aws. Each tool has an associated permission level indicated by asterisks. The use_aws tool is highlighted with "trust read-only commands" permission. At the bottom, there's a note stating "Trusted tools will run without confirmation" and a tip to "Use /tools help to edit permissions".

Figure 1: Tools selection in Amazon Q Developer CLI

Real-World Troubleshooting Scenario

Demonstration Environment Setup

This demonstration was performed with the following environment configuration:

The environment includes a local development machine with necessary tools, appropriate AWS account permissions, and terminal access. By starting Amazon Q Developer CLI in the project directory, it has immediate access to relevant code and configuration files.

Scenario: Troubleshooting NGINX 5XX Errors

The scenario demonstrates troubleshooting a multi-tier application architecture as shown in figure 2 deployed on Amazon ECS Fargate with:

  • Application Load Balancer (ALB) distributing traffic across availability zones
  • NGINX reverse proxy service handling incoming requests
  • Node.js backend service processing business logic
  • Service discovery enabling internal communication
  • CloudWatch Logs providing centralized logging

An AWS cloud architecture diagram showing the flow of traffic from an Internet user through multiple components. The diagram includes: At the top: An Internet user connecting to an Internet Gateway Within a VPC (Virtual Private Cloud): Two public subnets containing a NAT Gateway and Application Load Balancer Two private subnets within an ECS Cluster containing: An NGINX service (Fargate) A Backend service (Fargate) A 10-second timeout between them A Cloud Map Service Discovery component at the bottom CloudWatch Logs integration on the right side The diagram includes a note about gateway timeouts: "504 Gateway Timeout - Backend takes 15s to respond, NGINX timeout is 10s" All components are connected with arrows showing the flow of traffic and data through the system. The infrastructure follows AWS best practices with public and private subnet separation for security.

Figure 2: AWS Architecture diagram for the app used in this blog post

Traditional Troubleshooting Steps

For the architecture in figure 2, when 502 Gateway Timeout errors occur, traditional troubleshooting requires:

  1. Checking ALB target group health
  2. Examining ECS service status across multiple consoles
  3. Analyzing CloudWatch logs from different log groups
  4. Correlating error patterns between services
  5. Reviewing infrastructure code for configuration issues
  6. Implementing and deploying fixes

Amazon Q Developer CLI Approach

Instead, let’s see how Amazon Q Developer CLI handles this systematically, step by step:

Step1: Initial Problem Report

Amazon Q Developer CLI is provided with the initial prompt as a problem statement within the application project directory as shown in the following screenshot in figure 3. Amazon Q Developer responds back and says it is going investigate the 502 Gateway Timeout errors in the NGINX application.

Prompt:

Our production NGINX application is experiencing 502 Gateway Timeout errors. 
I have checked out the application and infrastructure code locally and the AWS CLI 
profile 'demo-profile' is configured with access to the AWS account where the 
infrastructure and application is deployed to. Can you help investigate and diagnose the issue?

A Visual Studio Code window showing a debugging session for an NGINX application. The interface has three main sections: a file explorer on the left showing project files including 'app.ts' and 'nginx-config-task.json', a terminal tab in the center displaying an "Amazon Q" ASCII art logo, and a conversation where a user is reporting 502 Gateway Timeout errors. The terminal shows AWS CLI command execution using a tool called "use_aws" with parameters including the service name "ecs" and region "us-west-2". The interface has red annotations highlighting key areas like "project files", "User provided initial prompt", and "Q CLI executing AWS CLI calls.

Figure 3: Amazon Q Developer CLI with initial prompt and problem statement

Step2: Systematic Infrastructure Discovery

Amazon Q Developer CLI start to systematically discovering the infrastructure as shown in the following screenshot in figure 4. If you see the initial prompt did not include that the app is hosted on ECS, but Amazon Q Developer CLI understood the context and executes the AWS CLI calls to describe the Cluster and the services within it. It made sure that the ECS tasks are running for both the services within the Cluster. It is a key discovery that both services show healthy status (1/1 desired count), indicating the issue isn’t service availability.

A terminal window showing three sequential AWS CLI commands being executed through a "use_aws" tool: First command: "list-clusters" operation for ECS service in us-west-2 region using demo-profile, completing in 1.244 seconds Second command: "list-services" operation targeting the NginxSimulationCluster, completing in 0.877 seconds with confirmation of finding both nginx-service and backend-service Third command: "describe-services" operation examining both services in detail, completing in 0.968 seconds with confirmation that both services are running as expected (1/1 desired count) Each command includes execution details, parameters, and completion status, with the system preparing to check CloudWatch logs next.

Figure 4: AWS Infrastructure discovery by Amazon Q Developer CLI

Step 3: Intelligent Log Analysis

Amazon Q Developer CLI retrieves and analyzes recent CloudWatch logs from the NGINX container, immediately identifying the critical error pattern as shown in the following screenshot in figure 5, where Amazon Q Developer responds: “Perfect! I found the issue. The NGINX logs show clear 504 gateway timeout with upstream timeout messages.”

A terminal window showing two AWS CloudWatch Logs commands being executed: First command: "describe-log-streams" operation for the "/ecs/nginx-service" log group, limiting to 5 most recent entries, ordered by LastEventTime in descending order Second command: "get-log-events" operation retrieving 50 log entries from a specific NGINX container log stream The output reveals a critical error message highlighted at the bottom showing an upstream timeout (error 110) occurring while reading response headers. The error details include client IP 10.0.0.247, upstream server at http://10.0.3.18:3000/, and host 52.35.62.210.

Figure 5: CloudWatch Log analysis by Amazon Q Developer CLI

Step 4: Amazon Q Developer CLI Analysis and Root Cause Identification

Amazon Q Developer examines backend service logs and discovers a mismatch between the backend service response time and NGINX timeout settings, as seen in the following screenshot in figure 6.

A terminal window showing AWS CloudWatch Logs commands and their output. The first command describes log streams for a backend container, and the second retrieves log events. The output reveals a debugging analysis showing that while health checks work fine, regular requests are being delayed by about 15 seconds, causing NGINX timeout issues. The log group is "/ecs/backend-service" in the us-west-2 region using a demo-profile.

Figure 6: Root cause identification by Amazon Q Developer CLI

Step 5: Amazon Q Developer CLI Root Cause Analysis

Amazon Q Developer CLI examines the ECS task definitions to identify the exact configuration mismatch, as shown in the following screenshot in figure 7. Amazon Q Developer finds that:

  • Backend service is configured with response_delay=15000 (15 secs)
  • NGINX proxy is configured with proxy_read_timeout 10s

This mismatch causes 504 gateway timeout errors when the backend response exceeds NGINX’s timeout threshold.

A terminal window showing two AWS CLI commands to describe ECS task definitions in the us-west-2 region. Below the commands is a highlighted "Root Cause Analysis" section that explains a timeout mismatch: the backend service is configured with a 15-second response delay while NGINX has a 10-second proxy timeout, resulting in 502 Gateway Timeout errors. Both commands use a demo-profile and are labeled as checking timeout and response delay configurations.

Figure 7: Root cause analysis and issue detection by Amazon Q Developer CLI

Step 6: Automated Code Fix

Here’s where Amazon Q Developer CLI truly excels—it doesn’t just diagnose; it implements the fix. Since Amazon Q Developer CLI is started within the project where the CDK code for ECS task definition is defined, it identified the code configuration and also modified it, as shown in the following screenshot in figure 8.

A terminal window showing file operations using fs_read and fs_write tools. The code changes show an NGINX configuration update in ecs-nginx-cdk.ts, where the proxy_read_timeout is being modified from '10s' to '20s'. The file also shows additional timeout configurations being added, including proxy_connect_timeout and proxy_send_timeout. The update is confirmed with a user prompt and completed in 0.2 seconds.

Figure 8: CDK code fix by Amazon Q Developer CLI

Step 7: Deployment

Amazon Q Developer CLI builds and deploys the fix by executing cdk synth and cdk deploy using the ‘demo-profile‘ AWS CLI profile that was initially provided in the prompt, as shown in the following screenshot in figure 9.

A terminal window showing two execute_bash commands running in sequence. The first command builds a CDK project using 'npm run build' in the nginx-app directory, completing in 4.102s. The second command deploys the updated CDK stack using 'cdk deploy' with the demo-profile, showing deployment progress including some warnings about minHealthyPercent configurations and CloudFormation stack updates in us-west-2 region.

Figure 9: CDK code build and deployment by Amazon Q Developer CLI

Step 8: Validation

Amazon Q Developer CLI validates the solution by sending a curl request to the ALB endpoint after the successful deployment, as shown in the following screenshot in figure 10.

A terminal window showing the execution of a curl command to test an NGINX application on AWS. The command targets an Elastic Load Balancer in the us-west-2 region. The response shows a successful HTTP 200 OK status after 14 seconds, with a JSON response containing the message "Hello from backend". The test completes in 15.100 seconds, indicating the fix for previous 502 errors was successful.

Figure 10: Fix validation by Amazon Q Developer CLI

In addition to that, Amazon Q Developer also sends a request to the health check endpoint and validates everything is working after the fix was deployed, as shown in the following screenshot in figure 11.

A terminal screenshot showing the results of a health check on an Nginx server using curl. The command executed shows a successful response with "healthy" status, completing in 0.65 seconds. The output displays various metrics including download speed (386 B/s), 100% completion rate, and timing statistics for real, user, and system processes.

Figure 11: Health endpoint validation by Amazon Q Developer CLI

What Amazon Q Developer CLI Accomplished

Using just conversational commands, Amazon Q Developer CLI performed a complete troubleshooting cycle:

  • Infrastructure Discovery: Automatically mapped ECS clusters, services, and dependencies
  • Log Correlation: Analyzed thousands of log entries across multiple services
  • Root Cause Analysis: Identified exact configuration mismatch between NGINX’s timeout (10s) and the backend’s response delay (15s)
  • Code-Level Diagnosis: Located problematic timeout setting in CDK infrastructure code
  • Automated Implementation: Modified infrastructure code to increase the NGINX timeout
  • End-to-End Deployment: Built, deployed, and validated the complete solution
  • Comprehensive Testing: Verified both fix effectiveness and overall system health

Amazon Q Developer CLI handles troubleshooting tasks through a single, conversational interface, eliminating the need for multiple tools or AWS CLI commands.

Conclusion

Amazon Q Developer CLI represents a significant evolution in how we troubleshoot cloud infrastructure issues. By combining natural language understanding with powerful command execution capabilities, it transforms complex troubleshooting workflows into efficient, action-oriented dialogues. Whether you’re dealing with NGINX 5XX errors or similar issues across other AWS services, Amazon Q Developer CLI can help you diagnose issues, implement fixes, and validate solutions—all through a conversational interface that feels natural and intuitive.

Give Amazon Q Developer CLI a try the next time you encounter a troubleshooting challenge, and experience the difference it can make in your operational workflow.

To learn more about Amazon Q Developer’s features and pricing details, visit the Amazon Q Developer product page.

About the Author

kirankumar.jpeg

Kirankumar Chandrashekar is a Generative AI Specialist Solutions Architect at AWS, focusing on Amazon Q Developer. Bringing deep expertise in AWS cloud services, DevOps, modernization, and infrastructure as code, he helps customers accelerate their development cycles and elevate developer productivity through innovative AI-powered solutions. By leveraging Amazon Q Developer, he enables teams to build applications faster, automate routine tasks, and streamline development workflows. Kirankumar is dedicated to enhancing developer efficiency while solving complex customer challenges, and enjoys music, cooking, and traveling.

Build a multi-Region AWS PrivateLink backed service with seamless failover

Post Syndicated from Madhav Vishnubhatta original https://aws.amazon.com/blogs/architecture/build-a-multi-region-aws-privatelink-backed-service-with-seamless-failover/

Global Payments Inc. is a leading worldwide provider of payment technology and software solutions, headquartered in Atlanta, Georgia. The company processes more than 75 billion transactions annually, serving more than 5 million merchant locations and nearly 2,000 financial institutions globally. Through its merger with TSYS in 2019, Global Payments expanded its capabilities beyond merchant acquiring services to include issuer processing solutions.

The company’s services now encompass ecommerce and omnichannel payments, business management software, customer engagement tools, and cloud-based solutions. Their commitment to technological innovation and customer service has positioned them as one of the largest financial technology companies globally, consistently ranking among the Fortune 500.

This post demonstrates how the Issuer Solutions business of Global Payments, as a service provider, implemented cross-Region failover for an AWS PrivateLink backed service exposed to their customers. Their solution enables failover to a secondary Region without customer coordination, reducing Recovery Time Objective (RTO).

AWS PrivateLink involves two key roles: service providers and service consumers. Service providers build, own, and manage endpoint services. Service consumers create and manage Amazon Virtual Private Cloud (Amazon VPC) endpoints that connect their VPC to an Amazon VPC endpoint service privately, without exposing the traffic to the public internet. Enterprises often build services in multiple AWS Regions for resilience. This approach requires endpoint services in two Regions, with service consumers creating VPC endpoints for each service.

The architecture uses Amazon Route 53 to resolve the service’s Fully Qualified Domain Name (FQDN) to the active Region’s service. Amazon Application Recovery Controller (ARC) is used to initiate the failover.

Customer requirements

Issuer Solutions had the following requirements for this implementation:

  • The ability for consumers to access the service privately, without traversing the public internet
  • Resilience to degradation in a single Region by allowing failover to a secondary Region
  • Independent failover without customer coordination
  • Reliable and simple failover process

Solution overview

The following simplified architecture diagram illustrates the connectivity and failover mechanisms. The exact service implementation of Issuer Solutions is beyond this post’s scope. For simplicity, we represent the service as a Network Load Balancer backed by Amazon Elastic Compute Cloud (Amazon EC2) instances.

AWS Architecture diagram showing primary and secondary regions with Route53 Private Hosted Zones, VPC endpoints, and PrivateLink integration, illustrating the connectivity and failover mechanisms.

The solution consists of the following key components:

  • The service provider deploys identical services in two Regions. The service is represented in this simplified version with a Network Load Balancer backed by EC2 instances. Each Region is independent and therefore resilient against failures in the other Region.
  • Services are exposed through PrivateLink as VPC endpoint services in each Region, allowing client connections without needing NAT gateways or internet gateways and keeping the traffic within the customers’ own private IP space.
  • The service provider authorizes the consumer AWS account to find the services using the VPC endpoint service names.
  • The service consumer uses the VPC PrivateLink endpoint service names to create VPC endpoints with Elastic Network Interfaces (ENIs) in two Availability Zones in each Region. The consumer does this in both consumer Regions, and each consumer Region has two sets of VPC endpoints: one for the primary service of the provider and one for the secondary service.
  • The service consumer creates a Route 53 private hosted zone in each of the two Regions they use, each with two alias records, with a simple routing policy, pointing to the VPC endpoints’ FQDNs in their own Regions. These two alias records are primary.example.com and secondary.example.com.
  • The service provider creates a Route 53 ARC cluster with routing controls for the primary and secondary Regions.
  • The service provider creates a private hosted zone with a failover record set for a consumer specific CNAME like custC.service.p.com that resolves to primary.example.com and secondary.example.com. These records are associated with health checks that are associated with Route 53 ARC routing controls.

As shown in the architecture diagram, it is not necessary for the provider’s and consumer’s Regions to be the same because AWS supports creating VPC endpoints in a Region different to that of the VPC endpoint service itself. Refer to AWS PrivateLink now supports cross-region connectivity for more details.

How the DNS resolution works

Each consumer Region has two Route 53 private hosted zones involved in DNS resolution in this approach: the service provider’s hosted zone and the service consumer’s hosted zone. Both hosted zones are associated with the VPC used by the service consumer. Here is how the DNS resolution works:

  1. When a client in the consumer VPC wants to reach the service, it uses the FQDN custC.service.p.com.
  2. The hosted zone in the service provider’s account resolves custC.service.p.com to either primary.example.com or secondary.example.com depending on the status of the health checks controlled by ARC. For now, let’s assume this resolves to primary.example.com.
  3. Next, primary.example.com resolves to the VPC endpoint FQDN com.amazonaws.vpce.<primary-region>.vpce-svcabc123 due to the hosted zone in the service consumer.

At the time of failover, the service provider will update the ARC health checks to turn off the primary control and turn on the secondary routing control. This causes the service provider’s hosted zone to resolve custC.service.p.com to secondary.example.com, which in turn resolves to the VPC endpoint FQDN in the secondary Region due to the service consumer’s hosted zone.

Considerations

With this setup, the service provider can fail over when they need to without the service consumer having to manually make any changes. This is especially useful for services that have multiple service consumers. Additionally, service consumers can make changes to the VPC endpoint as they see fit. They only need to update the hosted zone they manage to make sure that primary.example.com and secondary.example.com point to the correct VPC endpoints.

We used ARC in this post because it offers a robust solution for cross-Region failover with built-in static stability. ARC also avoids single points of failure in the failover logic by distributing it across multiple Regions.

This setup demonstrates an active-passive configuration where traffic is routed to a single Region at a time using the Route 53 failover routing policy. For an active-active approach, you can adapt this setup by employing alternative Route 53 policies such as weighted or latency-based routing, as detailed in Active-active and active-passive failover.

Code sample

We have created a GitHub repository with Terraform code to demonstrate this solution. The repository has the steps to set it up and test it.

Conclusion

This implementation of cross-Region failover by Global Payments Issuer Solutions for their PrivateLink backed service demonstrates a robust and flexible approach to providing high availability and resilience. By using AWS services such as PrivateLink, Route 53, and Route 53 ARC, they have created a solution that meets their key requirements. This architecture not only benefits Global Payments by allowing them to manage failovers efficiently, but also provides advantages to their service consumers. Customers maintain control over their own infrastructure while benefiting from seamless service continuity. As cloud architectures continue to evolve, solutions like this showcase the power of combining various AWS services to create highly available and fault-tolerant systems that meet complex business needs.

Clone our GitHub repository now and deploy this solution in your own AWS environment to try out this approach to cross-Region failover. Contact your AWS representative today to begin your journey toward enhanced business continuity.


About the Authors

How Stellantis streamlines floating license management with serverless orchestration on AWS

Post Syndicated from Göksel SARIKAYA original https://aws.amazon.com/blogs/architecture/how-stellantis-streamlines-floating-license-management-with-serverless-orchestration-on-aws/

This post is written by Goeksel Sarikaya, Senior Delivery Consultant at AWS, and Milosz Stawarski, Senior Software Architect at Stellantis.

Software licensing is a critical aspect of many organizations’ operations, with various models available to suit different needs. Two common types are named user licenses, which are assigned to specific individuals, and floating licenses, which can be shared among a pool of users. Some independent software vendors (ISVs) offer both options, whereas others might have limitations, particularly in cloud environments.

In this post, we explore a unique scenario where an ISV, unable to provide a floating license option for cloud usage, worked with Stellantis to develop an alternative solution. This approach, implemented with the ISV’s permission, treats named user licenses as if they were floating, automatically assigning and removing them based on the state of user workbench instances.

This solution is not intended to circumvent licensing terms or reduce costs at the expense of ISVs. Rather, it’s a collaborative approach to address specific customer needs when traditional floating licenses aren’t available. We will demonstrate how the solution uses serverless AWS services like Amazon EventBridge, AWS Lambda, Amazon DynamoDB, and AWS Systems Manager, keeping in mind that any similar implementation should only be pursued with explicit permission from the software vendor.

Overview of Stellantis

Stellantis N.V., born from the merger of FCA and PSA Group, leads the change towards software defined vehicles (SDV). As part of this transformation, AWS and Stellantis created the Virtual Engineering Workbench (VEW), a modular framework to develop, integrate, and test vehicle software in the cloud, ultimately connecting their vehicles to the cloud.

The VEW provides predefined environments tailored to specific use cases. These environments come fully equipped with the tools, integrated development environments (IDEs), and licensing necessary for developers to jumpstart their projects.

For more details on VEW, refer to Stellantis’ SDV transformation with the Virtual Engineering Workbench on AWS.

Overview of solution

As the number of developers and projects grew, Stellantis faced a challenge in managing the limited number of named user licenses for their software tools. The manual process of assigning and revoking licenses became increasingly time-consuming and inefficient, potentially hindering the agility and productivity of their development teams.

Stellantis and AWS tackled this challenge head-on by collaborating on an innovative, dynamic license management solution using AWS serverless services. This solution transforms the traditional named user license model into a more flexible floating license system, automatically assigning and revoking licenses based on the state of user workbench instances. The licenses and solution discussed in this post pertain solely to the use of standalone software tools such as those used in automotive domains. These do not involve sharing of user data or content when licenses are reused.

Before we dive into the detailed workflow of the solution, let’s examine the high-level architecture. The following diagram illustrates how various AWS services work together to create this efficient license management system.

Multi-region AWS license management architecture showing event-driven workflows between toolchain and user accounts with VEW workbench integration

Architecture

This architecture uses key AWS services such as EventBridge, Lambda, DynamoDB, and Systems Manager to create a scalable, serverless solution that significantly reduces administrative overhead and optimizes license utilization.

In the following sections, we explore each component of this architecture in detail, explaining how they interact to provide a seamless license management experience for Stellantis’ VEW.

In workbench accounts (user accounts)

The design is serverless and based on an event-driven approach. The workflow in the user accounts is as follows:

  1. Workbench instances are Amazon Elastic Compute Cloud (Amazon EC2). Their start and stop automatically sends AWS events.
  2. An EventBridge rule invokes a Lambda function when such an event occurs. This function checks the tags on the EC2 instance to distinguish workbenches from other EC2 instances. Two tags are important for identifying workbench instances: vew:workbench:ownerId and vew:workbench:type.
  3. The Lambda function creates a custom event with the following data: user-id, workbench-type, workbench-state, and instance-id, and sends this event to the default event bus.
  4. An EventBridge rule forwards the custom event to a custom event bus in the license server account.

In license server account

The following steps take place in the license server account:

  1. An EventBridge rule invokes a Lambda
  2. This function interacts with a DynamoDB table that stores a mapping of licensed products to users. The function does the following:
    1. Deduces the licensed products present in the workbench from the workbench type.
    2. For each licensed product, it verifies if the combination of product and user is already present in the DynamoDB
    3. If the workbench is starting:
      1. If the combination is already present, it increases the count of workbenches in the table for this item by 1.
      2. If the combination is not present, it creates a new item in the table (product, user-id, workbench-count, timestamp).
    4. If the workbench is stopping, it decreases the count of workbenches in the table for this item by 1. If the count becomes 0, the item is deleted.
  3. Any update to the DynamoDB table triggers another Lambda
  4. If the change in the table is a creation of a new entry or deletion of an entry, this function writes the current timestamp to a Systems Manager parameter in both cases. This is so that if no changes are detected in the database, we don’t unnecessarily run the xLC (License Client for related product) caller function.
  5. Another Lambda function is invoked every minute. It compares the timestamp written in the Systems Manager parameter indicating a DynamoDB item creation or deletion with the last time the function called the xLC CLI to assign users to a license.
  6. If the DynamoDB timestamp is earlier, the function stops. If the DynamoDB timestamp is later, the function queries the table for obtaining the user-id for each product.
  7. To maintain a comprehensive record of license assignment operations, you can enable data plane events for DynamoDB in AWS CloudTrail.
  8. For each licensed product, the function uses Run Command, a capability of Systems Manager, to invoke the xLC CLI API on the license server to assign named users to a license for a product. The function provides the list of users assigned to the product to the API. This updates the named user list on the license server—the list is completely overwritten, which includes adding new user IDs and removing ones that are no longer needed.

Benefits and key features

The solution offers the following benefits:

  • Automated license assignment and removal – Users are automatically assigned licenses when their workbench instances start, and licenses are returned to the pool when instances stop, providing efficient license utilization.
  • Scalable and serverless architecture – The solution is built on serverless AWS services, allowing it to scale seamlessly as the number of users and workbench instances grows, without the need for provisioning or managing servers.
  • Centralized license management – The license server account acts as a central hub for managing licenses across multiple workbench accounts, simplifying administration and providing a unified view of license usage.
  • Reduced administrative overhead – By automating the license assignment and removal process, the solution can significantly reduce the administrative burden associated with manual license management.
  • Optimized license utilization – Licenses are assigned only when needed and returned to the pool when no longer required, maximizing license availability and minimizing idle licenses.
  • Monitoring and metrics – The solution provides monitoring capabilities and license usage metrics, enabling better visibility and informed decision-making regarding license procurement and allocation.

Conclusion

By implementing this serverless solution, it is possible to transform a manual named user license management systems to an automated floating license system for software tools. The event-driven architecture and serverless components provide efficient and scalable license assignment and removal based on the workbench instance state.

This solution has streamlined the license management process, reducing administrative overhead and optimizing license utilization. It is now possible to provision software tools more efficiently, improving productivity and resource allocation across the organization. Additionally, the centralized license management and monitoring capabilities provide better visibility and control over license usage, enabling informed decision-making and cost optimization.

Overall, this AWS based floating license solution has empowered organizations to use software tools more effectively, while minimizing the operational burden associated with license management. For more serverless learning resources, visit Serverless Land.


About the authors

How Nexthink built real-time alerts with Amazon Managed Service for Apache Flink

Post Syndicated from Nikos Tragaras, Raphaël Afanyan original https://aws.amazon.com/blogs/big-data/how-nexthink-built-real-time-alerts-with-amazon-managed-service-for-apache-flink/

This post is cowritten with Nikos Tragaras and Raphaël Afanyan from Nexthink.

In this post, we describe Nexthink’s journey as they implemented a new real-time alerting system using Amazon Managed Service for Apache Flink. We explore the architecture, the rationale behind key technology choices, and the Amazon Web Services (AWS) services that enabled a scalable and efficient solution.

Nexthink is a pioneering leader in digital employee experience (DEX). With a mission to empower IT teams and elevate workplace productivity, Nexthink’s Infinity platform offers real-time visibility into end user environments, actionable insights, and robust automation capabilities. By combining real-time analytics, proactive monitoring, and intelligent automation, Infinity enables organizations to deliver an optimal digital workspace.

In the past 5 years, Nexthink completed its transformation into a fully-fledged cloud platform that processes trillions of events per day, reaching over 5 GB per second of aggregated throughput. Internally, Infinity comprises more than 300 microservices that use the power of Apache Kafka through Amazon Managed Service for Apache Kafka (Amazon MSK) for data ingestion and intra-service communication. The Nexthink ecosystem includes several hundreds of Micronaut-based Java microservices deployed in Amazon Elastic Kubernetes Service (Amazon EKS). The vast majority of microservices interact with Kafka through the Kafka Streams framework.

Nexthink alerting system

To help you understand Nexthink’s journey toward a new real-time alerting solution, we begin by examining the existing system and the evolving requirements that led them to seek a new solution.

Nexthink’s existing alerting system provides near real-time notifications, helping users detect and respond to critical events quickly. While effective, this system has limitations in scalability, flexibility, and real-time processing capabilities.

Nexthink gathers telemetry data from thousands of customers’ laptops covering CPU usage, memory, software versions, network performance, and more. Amazon MSK and ClickHouse serve as the backbone for this data pipeline. All endpoint data is ingested in Kafka multi-tenant topics, which are processed and finally stored in a ClickHouse database.

Using the current alerting system, clients can define monitoring rules in Nexthink Query Language (NQL), which are evaluated in near real time by polling the database every 15 minutes. Alerts are triggered when anomalies are detected against client-defined thresholds or long-term baselines. This process is illustrated in the following architecture diagram.

Originally, database-polling allowed great flexibility in the evaluation of complex alerts. However, this approach placed heavy stress on the database. As the company grew and supported larger customers with more endpoints and monitors, the database experienced increasingly heavy loads.

Evolution to a new use-case: Real-time alerts

As Nexthink expanded its data collection to include virtual desktop infrastructure (VDI), the need for real-time alerting became even more critical. Unlike traditional endpoints, such as laptops, where events are gathered every 5 minutes, VDI data is ingested every 30 seconds—significantly increasing the volume and frequency of data. The existing architecture relied on database polling to evaluate alerts, running at a 15-minute interval. This approach was inadequate for the new VDI use case, where alerts needed to be evaluated in near real time on messages arriving every 30 seconds. Merely increasing the polling frequency wasn’t a viable option because it would place excessive load on the database, leading to performance bottlenecks and scalability challenges. To meet these new demands efficiently, we shifted to real-time alert evaluation directly on Kafka topics.

Technology options

As we evaluated solutions for our real-time alerting system, we analyzed two main technology options: Apache Kafka Streams and Apache Flink. Each option had benefits and limitations that needed to be considered.

All Nexthink microservices up to that point integrated with Kafka using Apache Kafka Streams. We’ve observed in practice multiple benefits:

  • Lightweight and seamless integration. No need for additional infrastructure.
  • Low latency using RocksDB as a local key-value store.
  • Team expertise. Nexthink teams have been writing microservices with Kafka-streams for a long time and feel very comfortable using it.

In some use cases however, we found that there were important limitations:

  • Scalability – Scalability was constrained by the tight coupling between parallelism of microservices and the number of partitions in Kafka topics. Many microservices had already scaled out to match the partition count of the topics they consumed, limiting their ability to scale further. One potential solution was increasing the partition count. However, this approach introduced significant operational overhead, especially with microservices consuming topics owned by other domains. It required rebalancing the entire Kafka cluster and needed coordination across multiple teams. Additionally, such modifications impacted downstream services, requiring careful reconfiguration of stateful processing. The alternative approach would be to introduce intermediate topics to redistribute workload, but this would add complexity to the data pipeline and increase resource consumption on Kafka. These challenges made it clear that a more flexible and scalable approach was needed.
  • State management – Services that needed to create large K-tables in memory had an increased startup time. Also, in cases where the internal state was large in volume, we found that it applied significant load to the Kafka cluster during the creation of the internal state.
  • Late event processing – In windowing operations, late events had to be managed manually with techniques that complexified the codebase.

Seeking an alternative that could help us overcome the challenges posed by our current system, we decided to evaluate Flink. Its robust streaming capabilities, scalability, and flexibility made it an excellent choice for building real-time alerting systems based on Kafka topics. Several advantages made Flink particularly appealing:

  • Native integration with Kafka – Flink offers native connectors for Kafka, which is a central component in the Nexthink ecosystem.
  • Event-time processing and support for late events – Flink allows messages to be processed based on the event time (that is, when the event actually occurred) even if they arrive out of order. This feature is crucial for real-time alerts because it guarantees their accuracy.
  • Scalability – Flink’s distributed architecture allows it to scale horizontally independently from the number of partitions in the Kafka topics. This feature weighed a lot in our decision-making because the dependence on the number of partitions was a strong limitation in our platform up to this point.
  • Fault tolerance – Flink supports checkpoints, allowing managed state to be persisted and ensuring consistent recovery in case of failures. Unlike Kafka Streams, which relies on Kafka itself for long-term state persistence (adding extra load to the cluster), Flink’s checkpointing mechanism operates independently and runs out-of-band, minimizing the impact on Kafka while providing efficient state management.
  • Amazon Managed Service for Apache Flink – Amazon Managed Service for Apache Flink is a fully managed service that simplifies the deployment, scaling, and management of Flink applications for real-time data processing. By eliminating the operational complexities of managing Flink clusters, AWS enables organizations to focus on building and running real-time analytics and event-driven applications efficiently. Amazon Managed Service for Apache Flink provided us with significant flexibility. It streamlined our evaluation process, which meant we could quickly set up a proof-of-concept environment without getting into the complexities of managing an internal Flink cluster. Moreover, by reducing the overhead of cluster management, it made Flink a viable technology choice and accelerated our delivery timeline.

Solution

After careful evaluation of both options, we chose Apache Flink as our solution due to its superior scalability, robust event-time processing, and efficient state management capabilities. Here’s how we implemented our new real-time alerting system.

The following diagram is the solution architecture.

The first use case was to detect issues with VDI. However, our intention was to build a generic solution that would give us the option to onboard in the future existing use cases currently implemented through polling. We wanted to maintain a common way of configuring monitoring conditions and allow alert evaluation both with polling as well as in real time, depending on the type of device being monitored.

This solution comprises multiple parts:

  • Monitor configuration – Using Nexthink Query Language (NQL), the alerts administrator defines a monitor that specifies, for example:
    • Data source – VDI events
    • Time window – Every 30 seconds
    • Metric – Average network latency, grouped by desktop pool
    • Trigger condition(s) – Latency exceeding 300 ms for a continual period of 5 minutes

This monitor configuration is then stored in an internally developed document store and propagated downstream in a Kafka topic.

  • Data processing using Generic Stream Services– The Nexthink Collector, an agent installed on endpoints, captures and reports various kinds of activities from the VDI endpoints where it’s installed. These events are forwarded to Amazon MSK in one of Nexthink’s production virtual private clouds (VPCs) and are consumed by Java microservices running on Amazon EKS belonging to several domains within Nexthink

One of them is Generic Stream Services, a system that processes the collected events and aggregates them in buckets of 30 seconds. This component works as self-service for all the feature teams in Nexthink and can query and aggregate data from an NQL query. This way, we were able to keep a unified user experience on monitor configuration using NQL, regardless of how alerts were evaluated. This component is broken down into two services:

    • GS processor – Consumes raw VDI session events and applies initial processing
    • GS aggregator – Groups and aggregates the data according to the monitor configuration
  • Real-time monitoring using Flink – Static threshold alerting and seasonal change detection, which identifies variations in data that follow a recurring pattern over time, are the two types of detection that we offer for VDI issues. The system splits the processing between two applications:
    • Baseline application – Calculates statistical baselines with seasonality using time-of-day anomaly algorithm. For example, the latency by VDI client location or the CPU queue length of a desktop pool.
    • Alert application – Generates alerts based on user-defined thresholds when the unexpected values don’t change over time or dynamic thresholds based on baselines, which trigger when a metric deviates from an expected pattern.

The following diagram illustrates how we join VDI metrics with monitor configurations, aggregate data using sliding time windows, and evaluate threshold rules, all within Apache Flink. From this process, alerts are generated and are then grouped and filtered before being processed further by the consumers of alerts.

  • Alert processing and notifications – After an alert is triggered (when a threshold is exceeded) or recovered (when a metric returns to normal levels), the system will assess their impact to prioritize response through the impact processing module. Alerts are then consumed by notification services that deliver messages through emails or webhooks. The alert and impact data are then ingested into a time series database.

Benefits of the new architecture

One of the key advantages of adopting a streaming-based approach over polling was its ease of configuration and management, especially for a small team of three engineers. There was no need for cluster management, so all we needed to do was to provision the service and start coding.

Given our prior experience with Kafka and Kafka Streams and combined with the simplicity of a managed service, we were able to quickly develop and deploy a new alerting system without the overhead of complex infrastructure setup. We used Amazon Managed Service for Apache Flink to spin up a proof of concept within a few hours, which meant the team could focus on defining the business logic without having concerns related to cluster management.

Initially, we were concerned about the challenges of joining multiple Kafka topics. With our previous Kafka Streams implementation, joined topics required identical partition keys, a constraint known as co-partitioning. This created an inflexible architecture, particularly when integrating topics across different business domains. Each domain naturally had its own optimal partitioning strategy, forcing difficult compromises.

Amazon Managed Service for Apache Flink solved this problem through its internal data partitioning capabilities. Although Flink still incurs some network traffic when redistributing data across the cluster during joins, the overhead is practically negligible. The resulting architecture is both more scalable (because topics can be scaled independently based on their specific throughput requirements) and easier to maintain without complex partition alignment concerns.

This significantly improved our ability to detect and respond to VDI performance degradations in real time while keeping our architecture clean and efficient.

Lessons learnt

As with any new technology, adopting Flink for real-time processing came with its own set of challenges and insights.

One of the primary difficulties we encountered was observing Flink’s internal state. Unlike Kafka Streams, where the internal state is by default backed by a Kafka topic from which its content can be visualized, Flink’s architecture makes it inherently difficult to inspect what is happening inside a running job. This required us to invest in robust logging and monitoring strategies to better understand what is happening during the execution and debug issues effectively.

Another critical insight emerged around late event handling—specifically, managing events with timestamps that fall within a time-window’s boundaries but arrive after that window has closed. Amazon Managed Service for Apache Flink addresses this challenge through its built-in watermarking mechanism. A watermark is a timestamp-based threshold that indicates when Flink should consider all events before a specific time to have arrived. This allows the system to make informed decisions about when to process time-based operations like window aggregations. Watermarks flow through the streaming pipeline, enabling Flink to track the progress of event time processing even with out-of-order events.

Although watermarks provide a mechanism to manage late data, they introduce challenges when dealing with multiple input streams operating at different speeds. Watermarks work well when processing events from a single source but can become problematic when joining streams with varying velocities. This is because they can lead to unintended delays or premature data discards. For example, a slow stream can hold back processing across the entire pipeline, and an idle stream might cause premature window closing. Our implementation required careful tuning of watermark strategies and allowable lateness parameters to balance processing timeliness with data completeness.

Our transition from Kafka Streams to Apache Flink proved smoother than initially anticipated. Teams with Java backgrounds and prior experience with Kafka Streams found Flink’s programming model intuitive and easy to use. The DataStream API offers familiar concepts and patterns, and Flink’s more advanced features could be adopted incrementally as needed. This gradual learning curve gave our developers the flexibility to become productive quickly, focusing first on core stream processing tasks before moving on to more advanced concepts like state management and late event processing.

The future of Flink in Nexthink

Real-time alerting is now deployed to production and available to our clients. A major success of this project was the fact that we successfully introduced a technology as an alternative to Kafka streams, with very little management requirements, guaranteed scalability, data-management flexibility, and comparable cost.

The impact on the Nexthink alerting system was significant because we no longer have a single evaluating alert through database polling. Therefore, we’re already assessing the timeframe for onboarding other alerting use cases to real-time evaluation with Flink. This will alleviate database load and will also provide more accuracy on the alert triggering.

Yet the impact of Flink isn’t limited to the Nexthink alerting system. We now have a proven production-ready alternative for services that are limited in terms of scalability due to the number of partitions of the topics they are consuming. Thus, we’re actively evaluating the option to convert more services to Flink to allow them to scale out more flexibly.

Conclusion

Amazon Managed Service for Apache Flink has been transformative for our real-time alerting system at Nexthink. By handling the complex infrastructure management, AWS enabled our team to deploy a sophisticated streaming solution in less than a month, keeping our focus on delivering business value rather than managing Flink clusters.

The capabilities of Flink have proven it to be more than an alternative to Kafka Streams. It’s become a compelling first choice for both new projects and existing feature refactoring. Windowed processing, late event management, and stateful streaming operations have made complex use cases remarkably straightforward to implement. As our development teams continue to explore Flink’s potential, we’re increasingly confident that it will play a central role in Nexthink’s real-time data processing architecture moving forward.

To get started with Amazon Managed Service for Apache Flink, explore the getting started resources and the hands-on workshop. To learn more about Nexthink’s broader journey with AWS, visit the blog post on Nexthink’s MSK-based architecture.


About the authors

Nikos Tragaras is a Principal Software Architect at Nexthink with around two decades of experience in building distributed systems, from traditional architectures to modern cloud-native platforms. He has worked extensively with streaming technologies, focusing on reliability and performance at scale. Passionate about programming, he enjoys building clean solutions to complex engineering problems

Raphaël Afanyan is a Software Engineer and Tech Lead of the Alerts team at Nexthink. Over the years, he has worked on designing and scaling data processing systems and played a key role in building Nexthink’s alerting platform. He now collaborates across teams to bring innovative product ideas to life, from backend architecture to polished user interfaces.

Simone Pomata is a Senior Solutions Architect at AWS. He has worked enthusiastically in the tech industry for more than 10 years. At AWS, he helps customers succeed in building new technologies every day.

Subham Rakshit is a Senior Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build streaming architectures so they can get value from analyzing their streaming data. His two little daughters keep him occupied most of the time outside work, and he loves solving jigsaw puzzles with them. Connect with him on LinkedIn.

Lorenzo Nicora works as a Senior Streaming Solutions Architect at AWS, helping customers across EMEA. He has been building cloud-centered, data-intensive systems for over 25 years, working across industries both through consultancies and product companies. He has used open source technologies extensively and contributed to several projects, including Apache Flink.

Powering global payout intelligence: How MassPay uses Amazon Redshift Serverless and zero-ETL to drive deeper analytics.

Post Syndicated from Yossi Shlomo original https://aws.amazon.com/blogs/big-data/powering-global-payout-intelligence-how-masspay-uses-amazon-redshift-serverless-and-zero-etl-to-drive-deeper-analytics/

Since the company was founded in 2019, MassPay’s singular objective has been to deliver frictionless global payments that power innovation and lift people, businesses, and quality of life worldwide. Today, the MassPay payment orchestration offering empowers companies to move money across borders effortlessly; enabling local payment experiences in over 175 countries and 70 currencies—including digital wallets, locally preferred alternative payment methods, and cryptocurrencies. From hyper-localized checkout experiences to instant global payouts, we orchestrate seamless financial experiences that reflect how people and businesses transact around the world.

As we have expanded globally, so has the complexity of our data. In this blog post we shall cover how understanding real-time payout performance, identifying customer behavior patterns across regions, and optimizing internal operations required more than traditional business intelligence and analytics tools. And how since implementing Amazon Redshift and Zero-ETL, we’ve seen 90% reduction in data availability latency, payments data available for analytics 1.5x faster, leading to 45% reduction in time-to-insight and 37% fewer support tickets related to transaction visibility and payment inquiries.

Unlocking deeper payout intelligence and global insights

To continue our innovation—and to continue to exceed our partners’ and customers’ expectations—we knew we needed to go beyond basic reporting. We know success is dependent upon developing a truly data-driven organization. This means tracking granular KPIs across payout success rates, payment method adoption, transaction velocity, customer onboarding funnel drop-off, and support ticket correlation. We also wanted to better forecast customer payment expectations, monitor foreign exchange cost trends, and understand market-specific nuances such as how payout timing impacts seller satisfaction in social commerce ecosystems.

“We didn’t just want more data. We wanted faster, smarter insights that would shape decisions in real time. Being a data-driven organization means our teams don’t guess. They know. And that gives us, our partners, and our customers real operational and competitive advantages.”

– Yossi Schlomo, Director of Payment Systems Architecture

MySQL databases, CSV exports, and third-party reporting tools wouldn’t support the scale or speed we needed to deliver.

Choosing AWS: A scalable and integrated analytics foundation

We chose Amazon Web Services (AWS) for our data infrastructure and to accelerate our analytics capabilities.

At the core of our stack is Amazon Redshift Serverless with AI-driven scaling and optimizations enabled, which gives us scalable, fast, and cost-efficient analytics without the burden of managing infrastructure. Coupled with Amazon Aurora MySQL-Compatible Edition as our transactional data store and Amazon Redshift zero-ETL integration, we eliminated manual data pipelines altogether. Transactional data flows into Amazon Redshift in near real-time, instantly powering dashboards, alerts, and machine learning (ML) models.

This data feeds interactive dashboards—both internally and embedded within our platform for customers. Now, executives, operations leads, and customer success teams can drill into payout performance by region, merchant, or payment method, while customers get real-time visibility into their own payout analytics as part of our platform experience. The architecture is shown in the following figure.

MassPay Zero-ETL architecture with Amazon Redshift Serverless

MassPay Zero-ETL architecture with Amazon Redshift Serverless

Why it’s different and what it unlocked

Without Amazon Redshift Serverless and zero-ETL, we would have had to invest in costly custom data pipelines, maintain separate exchange, transform, and load (ETL) infrastructure, and manually manage data freshness. The integration with Aurora MySQL-Compatible is seamless and reduces our analytics latency from minutes to seconds.

“Our differentiator is simple: We operationalize not just transactions but analytics for global payments. Most platforms can tell you if a transaction went through. For payments and payouts, MassPay can tell you how fast it went, what it cost, what method was most effective, and what that means for your business in real time.”

– Yossi Schlomo, Director of Payment Systems Architecture

Embedded intelligence, built for scale

Every MassPay customer gets access to comprehensive payment analytics. These are accessed using our API or through a white-label dashboard (shown in the following figure). This detail is core to our product and central to our value proposition. As part of our go-to-market strategy, we showcase these capabilities in every demo, and they’ve proven to be key drivers in conversion and upsell conversations, especially with platforms targeting high-growth ecosystems.We use tiered pricing models based on transaction volume, and our embedded intelligence helps our partners and customers optimize usage and scale efficiently.

MassPay Dashboard

MassPay Dashboard

What we’ve gained

Since implementing Amazon Redshift and Zero-ETL, we’ve seen measurable results including:

  • 90% reduction in data availability latency and data available for analytics 1.5x faster
  • 45% reduction in time-to-insight across payment and payout intelligence reports
  • 37% fewer support tickets related to transaction visibility and payment inquiries
  • Real-time Net Promoter Score (NPS) tracking correlates with payout success metrics, driving faster resolution paths

What’s next

We’re now extending our analytics model to include more advanced ML-based payout failure prediction and ML-based payment authorization prediction, FX optimization alerts, partner-level and network-level benchmarking, and much more.

Conclusion

MassPay isn’t just payments. We aren’t just payouts. We are the engine powering modern commerce. With AWS, we’re turning complex global payments infrastructure into a smart, transparent, and scalable platform for insights. For our partners, and for our customers, this means better decisions, faster payment processing, faster payouts, and truly global reach without guesswork.

We encourage you to leverage below resources to explore these features further


About the authors

Yossi Shlomo serves as the Director of Payment Systems Architecture at MassPay. Yossi is an expert in credit card payment systems, PCI compliance, and secure transaction architecture, helping global platforms process payments at scale with confidence. He specializes in building scalable, cloud-based transaction systems and optimizing global payment gateways for performance and reliability.

Milind Oke is a Amazon Redshift and SageMaker Lakehouse specialist Solutions Architect as AWS. He is based out of New York and has been building enterprise data platforms, data warehousing, and analytics solutions for customers across various domains over two decades. In the 5 years with AWS, Milind has been a speaker at worldwide technical conferences and is co-author of Amazon Redshift: The Definitive Guide: Jump-Start Analytics Using Cloud Data Warehousing 1st Edition.

How Launchpad from Pega enables secure SaaS extensibility with AWS Lambda

Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/architecture/how-launchpad-from-pega-enables-secure-saas-extensibility-with-aws-lambda/

Large organizations increasingly adopt software as a service (SaaS) solutions to focus on business priorities, reduce infrastructure management overhead, and optimize costs. These organizations expect SaaS vendors to provide customizability facilities for tailoring the solution behavior according to their needs. Although traditional approaches like feature flags and webhooks offer some flexibility, they often fall short of providing a high degree of customizability. A new emerging pattern in this space is tenant-supplied custom code execution, which allows tenants to inject their own code into specific workflow points, enabling deep customization while preserving the core SaaS solutions’ integrity and security.

In this post, we share how Pegasystems (Pega) built Launchpad, its new SaaS development platform, to solve a core challenge in multi-tenant environments: enabling secure customer customization. By running tenant code in isolated environments with AWS Lambda, Launchpad offers its customers a secure, scalable foundation, eliminating the need for bespoke code customizations.

Solution overview

Launchpad, which is built on AWS, is an end-to-end platform on which software providers can build, launch, and operate workflow-centric B2B SaaS applications and AI solutions. It provides a managed, secure, scalable cloud environment for hosting multi-tenant applications and data. It accelerates the build experience with generative AI-powered low code tools, prebuilt capabilities, and subscriber-level configuration. Being a multi-tenant platform at its core, Launchpad had to maintain stringent isolation across tenants in its architecture.

One of the requirements Launchpad had was to allow their tenants to augment the workflows natively by providing custom code. Some common scenarios included communicating with external systems with proprietary non-industry-standard protocols, reuse of existing business logic, and SDK-based custom code development.

The solution necessitated the ability for tenants to provide custom code that would implement the required business logic, which Launchpad would be executing. This required architecting a secure runtime environment for custom code execution that maintains the highest degree of cross-tenant isolation within the multi-tenant architecture, at the same time allowing sufficient access to platform APIs and services. It was essential to build an architecture that would decouple the environment running tenant code from the core SaaS platform, as illustrated in the following diagram.

Architecting the solution topology

To achieve the required high level of compute isolation for running code provided by different tenants, Launchpad has adopted Lambda functions in its architecture as the secure ephemeral compute environment. Each untrusted code snippet provided by tenants is bootstrapped as a stand-alone Lambda function, with strong Firecracker-based isolation across different functions and execution environments addressing Launchpad’s requirements. This isolation provides dedicated resources, customizable access permissions, independent monitoring and operations, and automatic scaling for each function, while maintaining complete separation from other functions and their execution environments, as illustrated in the following diagram.

With Lambda being a serverless compute service, adopting it for the Launchpad architecture yielded several significant benefits. The major business benefit was that tenants could implement thousands of custom workflow augmentations on their own simply by providing code snippets, instead of the Launchpad engineering team being responsible for implementing them in the core platform code. Other benefits included:

  • Managed runtimes – AWS handles patching and updating the underlying infrastructure, operating system, and runtimes for customers, reducing the potential attack surface.
  • Fine-grained permissions – Each function can have its own set of access policies to tightly control what resources and actions it can access.
  • No need to pre-provision and pay for overprovisioned capacity – Lambda functions scale up and down automatically based on traffic patterns.
  • Built-in monitoring – Lambda functions emit detailed metrics, logs, and traces through Amazon CloudWatch and AWS X-Ray out of the box, making it straightforward to monitor tenant code execution.

To further reduce risks, Launchpad runs these Lambda functions with untrusted code in a dedicated AWS account. This account is separated from the core SaaS platform account. When end-users create a new function in the Launchpad authoring portal, they upload their code and specify the code handler to be executed during the invocation. Users can also map function input and output to Launchpad fields for further processing to enable an even higher degree of customizability and integration. The multi-tenant authoring service is a Control Plane component that runs as a microservice on the Amazon Elastic Kubernetes Service (Amazon EKS) cluster and uses the Lambda API for function lifecycle management, as illustrated in the following diagram. After a function resource is created, it can be used for further invocations.

Runtime architecture

At runtime, when Launchpad needs to invoke a function, it calls the Lambda Invoke API. Before the function is invoked, the multi-tenant runtime service performs a tenancy check to make sure the request is coming from an authorized tenant by doing the token validation. After a successful validation, the service invokes the required Lambda function. To invoke functions hosted in a different AWS account, the multi-tenant runtime service uses an AWS Identity and Access Management (IAM) role to assume the required permissions and invokes the Lambda service using the AWS SDK. The sequence of interactions is shown in the following architecture diagram.

The workflow consists of the following steps:

  1. An incoming user request reaches the application gateway service.
  2. The application gateway authenticates the request using the tenancy security service.
  3. After it’s authenticated, the request is forwarded to the multi-tenant runtime service
  4. The multi-tenant runtime service validates the supplied token and performs a tenancy check. This makes sure tenants can only invoke own functions they have permissions for (for example, functions they own).
  5. The multi-tenant runtime service pod assumes the IAM role required for invoking the tenant-specific Lambda function in a different AWS account.
  6. The multi-tenant runtime service pod invokes the required Lambda function.

Invoking the platform API from custom code is as straightforward as connecting to any external API. The custom code can authenticate with the platform using OAuth2. To facilitate the authentication, the developer can pass along the credentials as input parameters to the function from the core platform. Then the developer can create a corresponding record (isolated by tenant) in the platform that stores the credentials per function, and pass credentials as input parameters during invocation.

Distributed architecture observability

Operating a distributed architecture that runs untrusted code across multiple AWS accounts requires a comprehensive observability strategy. Launchpad’s approach combines centralized logging and monitoring with cross-account aggregation to provide a unified operational view of the platform.

The monitoring architecture uses CloudWatch Metrics to observe the Lambda functions, aggregating them through a centralized observability layer. This setup empowers platform operators to correlate Lambda function metrics with the core platform services running on Amazon EKS. Launchpad also collects per-function telemetry like function invocations, error rates, and execution time, which allows them to observe per-tenant metrics. These telemetry dimensions enable both a platform-wide and tenant-specific monitoring perspective.

For logging and troubleshooting, Launchpad implements a unified logging pipeline that aggregates Lambda function logs with application gateway and runtime service logs. Each request flowing through the system carries a correlation ID, so operators can trace execution paths across the core SaaS services and into the tenant functions running in the AWS account running tenant Lambda functions.

With this multi-layer observability architecture, Launchpad can maintain operational excellence while running tenant code securely at scale. Regular operational reviews drive continuous improvements in monitoring coverage and incident response procedures. Having per-tenant Lambda functions make it possible for Launchpad to use tenant-specific cost allocation tags, further empowering them to understand the cost footprint of running tenant custom code.

Best practices

When building a SaaS solution, maintaining a unified core code base is essential for scalability and manageability. Implementing per-tenant variations within the core platform code can lead to maintenance complexity and technical debt. Instead, architect your SaaS solution to have extension points, which allow your tenants to inject their custom code at specific points in the workflow, enabling customization without compromising the platform’s maintainability. This pattern makes sure the core SaaS platform remains clean and standardized while offering the flexibility that customers demand.

Additional best practices include:

  • Use separate accounts for running Lambda functions with untrusted tenant-provided code to make sure it’s isolated from your core SaaS platform code.
  • Grant absolute minimum required access permissions to the execution role assigned to the function. The custom code running within the execution environment gets permissions defined in the execution role when making requests to AWS API endpoints. If the function doesn’t need to reach out to AWS API endpoints, remove all permissions from the execution role and add an explicit AWSDenyAll policy.
  • Use separate Lambda functions for each code snippet and each tenant. This will provide the highest degree of cross-tenant isolation. Resources are not reused across different functions and execution environments.
  • Use Lambda layers in case you need to add a layer of vendor-provided code in order to keep it separated from the untrusted tenant-provided code.
  • Implement additional security controls, such as using Amazon Virtual Private Cloud (Amazon VPC) constructs to restrict network access and VPC Flow Logs for network activity monitoring.

Conclusion

The implementation of a secure untrusted code execution environment within SaaS platforms addresses a critical need for tenant customization while maintaining architectural integrity. Lambda offers a built-in isolation model, fine-grained security controls, and serverless scalability, so SaaS providers such as Launchpad can address the requirements of executing tenant-provided code in a multi-tenant environment and offer robust customization capabilities while maintaining strict security boundaries and operational efficiency. This architectural pattern enables providers to focus on core platform development while confidently supporting tenant-specific workflows through the secure and scalable Lambda execution environment.

To learn more, refer to the Security Overview of AWS Lambda white paper. For additional serverless architectural patterns, see Serverlessland.com.


About the authors

PackScan: Building real-time sort center analytics with AWS Services

Post Syndicated from Sairam Vangapally original https://aws.amazon.com/blogs/big-data/packscan-building-real-time-sort-center-analytics-with-aws-services/

Amazon manages a complex logistics network with multiple touch points, from fulfillment centers to sort centers to final customer delivery. Among these, sort centers play a crucial role in the middle mile, providing faster and more efficient package movement. Within Amazon’s Middle Mile operations, high-volume sort centers process millions of packages daily, making immediate access to operational data essential for optimizing efficiency and decision-making. Real-time visibility into key metrics—such as package movements, container statuses, and associate productivity—is critical for smooth logistics operations. To address the need for real-time operational planning, the Amazon Middle Mile team developed PackScan, a cloud-based platform designed to provide instant insights across the network. By significantly reducing data latency, PackScan enables proactive decision-making, so teams can monitor inbound package flows, optimize outbound shipments based on live data, track associate productivity, identify bottlenecks, and enhance overall operational efficiency—all in real time.

In this post, we explore how PackScan uses Amazon cloud-based services to drive real-time visibility, improve logistics efficiency, and support the seamless movement of packages across Amazon’s Middle Mile network.

Prerequisites

This post assumes a foundational understanding of the following services and concepts:

Although hands-on experience is not required, a conceptual understanding of these services will help in understanding the architecture, design patterns, and components discussed throughout the article.

Business challenges

Amazon’s sort centers handle over 15 million packages daily across more than 120 facilities in North America. Given this scale, even minor delays in operational insights can lead to inefficiencies, increased costs, and escalations. Traditionally, data latencies of up to an hour have restricted the ability to make proactive decisions, directly affecting productivity, resource allocation, and responsiveness—especially during peak periods like holiday seasons and big deal days.

Without immediate visibility into package movements, container statuses, and associate performance, operational teams face challenges in identifying and resolving bottlenecks in real time. The lack of timely insights can disrupt the flow of packages, leading to shipment delays, reduced throughput, and suboptimal facility performance. Addressing these inefficiencies required a solution capable of delivering real-time, high-fidelity data to support rapid decision-making.

To bridge this gap, Amazon’s Middle Mile organization needed a scalable platform that could enhance visibility, minimize latency, and provide up-to-the-minute insights into logistics operations. PackScan was designed to meet these demands, giving teams access to the real-time data necessary to optimize workflows, mitigate bottlenecks, and improve overall efficiency.

Data flow

In 2024, PackScan was deployed across 80 sort centers in the USA, enabling real-time package analytics. The solution powers Grafana dashboards, which refresh every 10 seconds by fetching live package data from OpenSearch Service. With this near real-time visibility, operations teams can monitor package movement and sorting efficiency across sort centers. The following diagram outlines how package scan data is ingested, processed, and made actionable.

Each sort center is equipped with hardware at inbound stations where packages arrive from trailers. Integrated barcode scanners automatically scan each package as it enters the sorting process. Every scan generates an SNS event, capturing key attributes such as the package ID, dimensions, the associate who performed the scan, and the timestamp and location of the scan.

After they’re generated, these SNS events are ingested into Data Firehose through a Lambda function, where the data undergoes real-time enrichment. During this process, additional attributes are appended, including the business logic rules. The enriched data is then streamed into OpenSearch Service, where events are indexed to enable fast and efficient querying. With the indexed package scan events available in OpenSearch Service, real-time analytics and monitoring become possible. The Grafana dashboards query this data every 10 seconds, providing operational insights into package inflow metrics and associate performance.

Solution overview

PackScan was implemented using a structured and scalable approach, using AWS cloud-based services to enable high-frequency data ingestion, real-time processing, and actionable insights. The architecture is designed to minimize latency while providing reliability, scalability, and operational efficiency. The solution is built around a serverless, event-driven architecture that dynamically scales based on data ingestion volumes. The architecture—illustrated in the following figure—enabled us to build a real-time data solution, utilizing the advantages of various AWS services to provide low-latency analytics, high scalability, and real-time operational insights across Amazon’s sort centers.

The following are the key components and features of the solution:

  • Real-time data processing – Lambda functions serve as the processing backbone of the system, handling 500,000 scan events per second. Each incoming event is processed by applying data transformations, enrichment, and validation before passing it downstream.
  • High-frequency data ingestion and streaming – Data Firehose is the primary ingestion pipeline, handling millions of scan events daily from thousands of barcode scanners across multiple sort centers. The Firehose streams handle incoming data of 12,000 PUT requests per second, maintaining smooth ingestion and low-latency streaming. Data retention policies are set to buffer and forward enriched events every 60 seconds or upon reaching 5 MB batch size, optimizing storage and processing efficiency.
  • Optimized querying and operational insights – OpenSearch Service is used to index and store the processed scan events, providing real-time querying and anomaly detection. The OpenSearch cluster consists of 12 data nodes (r5.4xlarge.search) and 3 primary nodes (r5.large.search), processing up to 10 GB of data per day with a rolling index strategy, where indexes are rotated every 24 hours to maintain query performance. The system supports concurrent queries per second, enabling logistics teams to perform rapid lookups and gain instant visibility into package movements.
  • Live visualization and dashboarding – Grafana, hosted on an m5.12xlarge EC2 instance, provides real-time visualization of key logistics metrics. The dashboards refresh every 10 seconds, querying OpenSearch and displaying up-to-the-minute package analytics. The setup includes multiple preconfigured dashboards, monitoring package flow at different inbound stations, and workforce efficiency. These dashboards support concurrent users, enabling supervisors and associates to track and optimize operations proactively. The following screenshot shows one of the real-time dashboards, with details of package flow by different routes within sort centers.

The entire PackScan architecture is designed for automatic scaling, adjusting dynamically based on data ingestion volume to maintain efficiency during peak and off-peak operations. This approach provides cost-effective resource utilization while maintaining high availability and performance.

Business outcomes

The implementation of PackScan has led to measurable improvements in operational efficiency, workforce productivity, and real-time decision-making across Amazon’s sort centers. By reducing data latency and enabling real-time insights, PackScan has transformed logistics operations in meaningful ways:

  • Widespread deployment – PackScan was deployed across 80 sort centers, supporting approximately 1,000 display monitors that provide real-time operational insights.
  • Significant reduction in data latency – Data latency dropped from approximately 1 hour to less than 1 minute, allowing for real-time operational responsiveness and minimizing workflow disruptions.
  • Proactive operational management – With dynamic workload balancing and instant bottleneck identification, supervisors can now address issues as they arise, leading to smoother operations and fewer escalations.
  • Boost in workforce productivity – The real-time performance feedback has enhanced associate engagement, resulting in a 25% increase in throughput per hour and 12% reduction in labor hours.

Overall, PackScan has redefined real-time logistics visibility within Amazon’s Middle Mile operations, empowering operational teams with actionable insights, enhanced workforce efficiency, and a data-driven approach to package movement and sort center performance.

Lessons learned and best practices

The deployment and scaling of PackScan provided valuable insights into optimizing real-time logistics visibility. Several key lessons and best practices emerged from this implementation:

  • Cloud architecture drives efficiency – Adopting Amazon technologies provides seamless scalability, reduced operational overhead, and lower infrastructure costs, while maintaining high reliability. The following table shows an approximate breakdown of monthly service costs observed in production. This is an estimation based on current pricing; we recommend checking the respective AWS service pricing pages to generate the most up-to-date quote. This architecture demonstrates that with combination of provisioned and serverless design, production-ready solutions can be built and scaled at a fraction of the cost of traditional infrastructure.
AWS Service Description Estimated Monthly Cost
Amazon EC2 Three EC2 instances of type m5.12xlarge hosting Grafana $1,700
AWS Lambda Streams SNS events to Data Firehose $4,000
Amazon Data Firehose Real-time data delivery with 12,000 records streaming to OpenSearch Service $1,500
Amazon OpenSearch Service Indexing and querying package scan events $28,000
  • Real-time visibility is a game changer – Immediate access to operational data enhances agility, enabling teams to make timely, data-driven decisions that prevent bottlenecks and improve throughput.
  • Continuous monitoring enhances decision-making – Operational dashboards should evolve with business needs. Regular monitoring and updates provide accuracy, usability, and relevance in driving informed decision-making.

By applying these best practices, PackScan has set a foundation for scalable, real-time logistics management, making sure that Amazon’s Middle Mile operations remain proactive, efficient, and highly responsive to changing business demands.

Conclusion

PackScan has successfully transformed real-time operational visibility within Amazon’s sort centers, addressing critical challenges in data latency, workforce productivity, and logistics efficiency. By using AWS services, particularly Data Firehose for real-time data delivery and OpenSearch Service for analytics, PackScan has enabled proactive decision-making, streamlined operations, and enhanced throughput in high-volume sort environments. Looking ahead, future enhancements will focus on further elevating operational intelligence and scalability, including:

  • Integrating predictive analytics to anticipate workflow bottlenecks and optimize resource allocation
  • Scaling the solution across additional operational scenarios, providing greater resilience and adaptability to dynamic logistics environments

With these advancements, PackScan will continue to drive operational excellence, cost-efficiency, and real-time decision-making capabilities, reinforcing Amazon’s commitment to innovation in logistics and supply chain management.

For those interested in implementing similar solutions, we recommend exploring AWS Serverless Architecture Patterns and the AWS Architecture Blog for additional insights and best practices in building scalable, real-time analytics solutions.


About the authors

Sairam Vangapally is a Data Engineer at Amazon with extensive experience architecting real-time, large-scale data platforms that power critical logistics operations across North America. He has led the design and deployment of end-to-end data pipelines, enabling high-throughput ingestion, transformation, and analytics at scale. He is passionate about building resilient data infrastructure and driving cross-functional collaboration to deliver solutions that accelerate operational insights and business impact.

Nitin Goyal serves as a Data Engineering Manager in Amazon’s Sort Center organization, where he leads initiatives to optimize operational efficiency across North American facilities. With over nine years of tenure at Amazon spanning multiple teams, he specializes in architecting high-performance data systems, with particular emphasis on real-time streaming pipelines, artificial intelligence, and low-latency solutions. His expertise drives the development of sophisticated operational workflows that enhance sort center productivity and effectiveness.

Improving platform resilience at Cash App

Post Syndicated from Dustin Ellis original https://aws.amazon.com/blogs/architecture/improving-platform-resilience-at-cash-app/

This post was coauthored with engineers at Cash App, including Ben Apprederisse (Platform Engineering Technical Lead), Jan Zantinge (Traffic Engineer), and Rachel Sheikh (Compute Engineer).

Cash App, a leading peer-to-peer payments and digital wallet service from Block, Inc., has grown to serve over 57 million users since its launch in 2013. Providing diverse offerings like instant money transfers, debit cards, stock and bitcoin investments, personal loans, and tax filing, Cash App continuously strives to make money more relatable, accessible, and secure. To meet this mission, their platform built on AWS must remain highly scalable and resilient.

Cash App has implemented resilience improvements across the entire technology stack, but for this post, we explore two enhancements implemented in 2024. First, we discuss how Cash App improved the resilience of its compute platform built on Amazon Elastic Kubernetes Service (Amazon EKS) by implementing a dual-cluster topology to reduce single points of failure. We also discuss how Cash App used AWS Fault Injection Service (AWS FIS) to conduct an Availability Zone power interruption scenario in non-production environments, preparing the platform team for real-world failures and ongoing regulatory requirements.

Moving to Amazon EKS

Cash App has used Amazon EKS as a shared platform for years, and in 2024, we migrated the last of our biggest and most critical services to it, driven by the ease of management and our strategy to run workloads in the cloud. This shift empowered our teams to focus more on application delivery and less on cluster management, abstracting away some of the complexity in operating Kubernetes clusters. With Amazon EKS, AWS is responsible for managing the Kubernetes control plane, which includes the control plane nodes, the ETCD database, and other infrastructure necessary for AWS to deliver a service offering with enhanced security features. As a consumer of Amazon EKS, we are still responsible for things like AWS Identity and Access Management (IAM), pod security, runtime security, networking, and cluster automatic scaling in the data plane for worker nodes. AWS refers to this as the Shared Responsibility Model; for more details, refer to Best Practices for Security. For a while, maintaining a single shared EKS cluster for each environment and AWS Region was acceptable and met our technical requirements.

Scaling challenges with a single shared EKS cluster

As Cash App’s shared EKS cluster grew and onboarded hundreds of microservices, we became an early adopter of the Karpenter Cluster Autoscaler, which improved application availability and cluster efficiency. Karpenter was designed to enhance node lifecycle management within Kubernetes clusters. It automates provisioning and deprovisioning of nodes based on the specific scheduling needs of pods, allowing for efficient scaling and cost optimization. We also reviewed and adopted many of the Amazon EKS Best Practices Guides for Reliability, Security, Networking, and Scalability.

Despite these efforts, in 2023, we realized having a single shared EKS cluster with hundreds of worker nodes had become a critical dependency in our cloud platform architecture, whereby standard operations like cluster upgrades posed a risk of impacting production traffic or causing downtime. Although we had a staging environment that allowed us to test new features and changes before rolling them out in production, it didn’t always reflect real traffic patterns that could allow impactful changes to go unnoticed in lower environments. For example, in late 2023, production traffic was briefly impacted due to a relatively new Kubernetes feature called API Priority and Fairness (APF) that introduced temporary control plane throttling following a cluster upgrade.

As a leader in the financial services industry, any interruption to our services directly impacts customers’ ability to transact and participate in the economy, so round-the-clock availability of our platform is essential. Following this incident, we reviewed and implemented the Kubernetes Control Plane best practices pertaining to APF and set up new detections in our observability platform to monitor things like FlowSchemas and queue depth. We also created a business case for investing in platform evolution and moving towards a multi-cluster topology. The desired state was to have a safer way to upgrade clusters, such that traffic is always serviceable regardless of the state of a single cluster in the fleet.

The following diagram illustrates our basic architecture in late 2023, portraying a single, Multi-AZ EKS cluster at Cash App. We had two ingress paths: for public ingress, we used Amazon Route 53 to a Network Load Balancer (NLB). For internal ingress across Amazon Virtual Private Cloud (Amazon VPC) networks (for example, from other business units), we set up a VPC endpoint service. Other components (such as service dependencies like database clusters and other Regions) are intentionally omitted from the diagram for simplicity.

Enterprise network architecture showcasing secure cross-VPC communication via PrivateLink to shared EKS cluster with public/internal ingress

Enterprise network architecture showcasing secure cross-VPC communication via PrivateLink to shared EKS cluster with public/internal ingress

Platform enhancements

In 2024, our cloud platform team implemented architectural changes to improve the reliability of the shared Amazon EKS platform, which was already running hundreds of services and over 10,000 pods. In the process, we also recognized the importance of chaos engineering to provide controlled failure testing and preparedness, which is also an evolving regulatory requirement for financial institutions. Our team has made multiple resilience improvements to apply long-term scalability; the rest of this post focuses on two enhancements we believe other AWS customers can benefit from.

Enhancement 1: Implementing a dual-cluster topology

When researching multi-cluster topologies and interacting with AWS specialists, we learned about architectural patterns to improve platform resilience with varying degrees of complexity. This included cell-based architecture, Route 53 weighted routing, and NLB chaining, among other patterns. Our initial requirements for the multi-cluster architecture were as follows:

  • Effortlessly deploy a service across two or more clusters
  • Serve production traffic from multiple clusters at the same time if needed
  • Seamlessly upgrade a production cluster without impacting production traffic
  • Have the ability to take a cluster out of the traffic flow during planned and unplanned events
  • Achieve reliability improvements with minimal architectural and cost changes

Based on these initial requirements and the complexity required to properly implement a cell-based architecture, we decided to start with Route 53 weighted routing for public ingress, and NLB chaining for internal ingress to achieve immediate improvements. Although we plan to implement a cell-based architecture in the future, it requires careful consideration and engineering investment (for example, creating a cell router and cell provisioning system). At the time, we needed a simpler, short-term solution that could improve overall scalability and reliability. From a Kubernetes perspective, we started with two Multi-AZ clusters in our production environment, each operating independently, such that a planned or unplanned event in one cluster would not affect the other cluster. Existing pipelines were extended to deploy the same Kubernetes resources into both clusters, which would actively serve ingress traffic using an NLB. If needed, we could divert all ingress traffic to one cluster during planned or unplanned events by updating the weights in Route 53 (for public ingress) or updating the listener rules and target groups on the frontend NLB (for internal ingress). In the following sections, we dive deeper into both approaches.

Public ingress changes

For public ingress, requests are still handled by Route 53. With the introduction of weighted routing, requests can be evenly routed between the two backend NLBs (one per cluster). This setup allows Cash App to split traffic evenly across clusters or temporarily route all traffic to one cluster during upgrades. As an example, during cluster A’s upgrade, we can direct ingress traffic to cluster B, enabling a sequential upgrade process with minimal disruption. This dual-cluster approach helps mitigate single points of failure and establishes a foundation for reliability improvements. The following diagram illustrates this architecture.

Highly available AWS Cash App architecture using Route 53 for 50/50 traffic distribution to dual NLB and EKS clusters across three AZs

Highly available architecture using Route 53 for 50/50 traffic distribution to dual NLB and EKS clusters across three AZs

Internal ingress changes

Cash App works closely with other business units like Square, and therefore needs to have a secure and scalable ingress path for cross-VPC traffic. To support these use cases, internal ingress requests are still routed from other business unit VPCs to the NLB associated with our VPC endpoint service. From there, requests are load balanced roughly evenly to two backend NLBs (one per cluster) using the listener rules. The following diagram illustrates this architecture.

Enterprise AWS Cash App architecture featuring secure VPC peering, tiered load balancing, and redundant EKS clusters for high availability

Cash App architecture featuring secure VPC peering, tiered load balancing, and redundant EKS clusters for high availability

Key considerations

Consider the following when assessing these approaches:

  • The NLB chaining approach used for internal ingress enables controlled failover and maintenance with minimal disruption by adjusting NLB listeners and target groups, and reduces single points of failure by distributing requests across two or more clusters.
  • Although this pattern met our initial requirements and made it possible to shift traffic from one cluster to another, it’s not as granular as we would like (for example, shift traffic for only service A to cluster B, and leave all other traffic on cluster A). We will continue to evolve the architecture and implement a more intelligent ingress router and cell provisioning system. Furthermore, at the time of writing, NLB doesn’t support weighted target group routing.
  • Using the NLB chaining approach adds additional cost due to multiple NLBs in the traffic path. With NLBs, you’re charged for each hour or partial hour that an NLB is running, and the number of Network Load Balancer Capacity Units (NLCUs) used by the NLB per hour.
  • The NLB chaining approach doesn’t achieve the full benefits of a cell-based architecture, which provides greater isolation and fault isolation boundaries. Moving to a cell-based architecture requires more complexity and coordination, so we decided to start with NLB chaining and Route 53 weighted routing for immediate improvements and minimal re-architecture.

Looking forward, we plan to implement a cell-based architecture that aligns with Block’s compute strategy. This will consist of a cell management layer (to create, update, and delete cells) and a cell routing layer (to route requests to the correct cell), which allows for fine-grained traffic routing.

Enhancement 2: Using AWS FIS for Availability Zone power interruption

After moving to a dual-cluster topology, we researched ways to test ongoing platform resilience. Specifically, we wanted to test what would happen to our environment during single Availability Zone impairments and how our services and data stores would recover. This led us to AWS FIS, which we could use to conduct an Availability Zone power interruption scenario in our staging environment. AWS FIS is a fully managed service for running fault injection experiments on AWS infrastructure, making it straightforward to get started with chaos engineering. Chaos engineering is the practice of stressing an application in testing or production environments by creating disruptive events, such as a sudden increase in CPU or memory consumption, observing how the system responds, and implementing improvements.

Our initial AWS FIS experiment used multiple actions, including network disruption, database failover (targeting Amazon Aurora and Amazon ElastiCache clusters), and EKS worker node disruption (pod eviction and rescheduling). For the full list of AWS FIS actions, refer to AZ Availability: Power Interruption. For our initial experiment, we targeted infrastructure in a single staging account; however, AWS FIS supports multi-account experiments by setting up an orchestrator account that enables centralized configuration, management, and logging. The orchestrator account owns the AWS FIS experiment template. For future AWS FIS experiments, we plan to target more accounts and resources, operating within the constraints of AWS FIS quotas and limits.

For clear communication during the AWS FIS experiment, our platform team coordinated with internal application stakeholders and our AWS account team, monitoring metrics to gauge failover and recovery responses. After the experiment, we debriefed with AWS teams and submitted product feature requests to support ongoing service evolution. Moving forward, we plan to conduct AWS FIS experiments at least twice a year to reinforce reliability best practices and adhere to ongoing regulatory requirements. We will also diversify the types of fault injection experiments we perform, and expand beyond the single Availability Zone failure tests. For example, we might introduce a capability that allows application teams to perform one-time AWS FIS experiments just for their service and backend database infrastructure in a controlled, self-service fashion. An added benefit of using AWS FIS is that there is no agent or infrastructure to deploy or manage, and you’re only billed for the duration of the experiment. This made it both straightforward and affordable to get started with chaos engineering. The following diagram illustrates the architecture of the Availability Zone power interruption scenario targeting subnets, compute, and database clusters.

AWS Fault Injection Service AZ Availability: Power Interruption scenario

AWS Fault Injection Service AZ Availability: Power Interruption scenario

Key considerations

Setting up the AWS FIS experiment required us to modify default service limits and quotas to accommodate the scale and scope, such as the number of target resources for ElastiCache, Amazon Relational Database Service (Amazon RDS), and subnets. We recommend reviewing the quotas, service limits, and supported services prior to conducting your own experiment, and collaborate with your AWS account team to achieve a seamless experience.

We also learned that certain failures, such as database failover, require more than network disruption actions alone—specific failover actions had to be configured in the AWS FIS experiment template to trigger the desired behavior, as outlined further in the service documentation. If you’re starting with the Availability Zone power interruption scenario, be sure to include all of the required actions to achieve the desired outcome. Finally, we recommend using AWS FIS in lower environments because AWS FIS actions will have real impact on the targeted resource state and availability.

Conclusion

Through these enhancements, Cash App has improved overall resilience posture and laid the groundwork for future improvements. On the Amazon EKS side, we aim to implement an ingress routing layer through cell-based architecture patterns, enabling more granular traffic routing and improved fault isolation boundaries. We will continue to use Karpenter for cluster automatic scaling, and are in the process of rolling out AWS Graviton based instances to further improve resource efficiency. Finally, we will continue using AWS FIS for chaos engineering at both the platform and application level, performing larger-scale AWS FIS experiments with more complexity.

For other blog posts and related resources, refer to:


About the authors

How Airties achieved scalability and cost-efficiency by moving from Kafka to Amazon Kinesis Data Streams

Post Syndicated from Steven Aerts, Reza Radmehr original https://aws.amazon.com/blogs/big-data/how-airties-achieved-scalability-and-cost-efficiency-by-moving-from-kafka-to-amazon-kinesis-data-streams/

This post was cowritten with Steven Aerts and Reza Radmehr from Airties.

Airties is a wireless networking company that provides AI-driven solutions for enhancing home connectivity. Founded in 2004, Airties specializes in developing software and hardware for wireless home networking, including Wi-Fi mesh systems, extenders, and routers. The flagship software as a service (SaaS) product, Airties Home, is an AI-driven platform designed to automate customer experience management for home connectivity, offering proactive customer care, network optimization, and real-time insights. By using AWS managed services, Airties can focus on their core mission: improving home Wi-Fi experiences through automated optimization and proactive issue resolution. This includes minimizing network downtime, enabling faster diagnostic capabilities for troubleshooting, and enhancing overall Wi-Fi quality. The solution has demonstrated significant impact in reducing both the frequency of help desk calls and average call duration, leading to improved customer satisfaction and reduced operational costs for Airties while delivering enhanced service quality to their customers and the end-users.

In 2023, Airties initiated a strategic migration from Apache Kafka running on Amazon Elastic Compute Cloud (Amazon EC2) to Amazon Kinesis Data Streams. Prior to this migration, Airties operated multiple fixed-size Kafka clusters, each deployed in a single Availability Zone to minimize cross-AZ traffic costs. Although this architecture served its purpose, it required constant monitoring and manual scaling to handle varying data loads. The transition to Kinesis Data Streams marked a significant step in their cloud optimization journey, enabling true serverless operations with automatic scaling capabilities. This migration resulted in substantial infrastructure cost reduction while improving system reliability, eliminating the need for manual cluster management and capacity planning.

This post explores the strategies the Airties team employed during this transformation, the challenges they overcame, and how they achieved a more efficient, scalable, and maintenance-free streaming infrastructure.

Kafka use cases for Airties workloads

Airties continuously ingests data from tens of millions of access points (such as modems and routers) using AWS IoT Core. Before the transition, these messages were queued and stored within multiple siloed Kafka clusters, with each cluster deployed in a separate Availability Zone to minimize cross-AZ traffic costs. This fragmented architecture created several operational challenges. The segmented data storage required complex extract, transform, and load (ETL) processes to consolidate information across clusters, increasing the time to derive meaningful insights. The data collected serves multiple critical purposes—from real-time monitoring and reactive troubleshooting to predictive maintenance and historical analysis. However, the siloed nature of the data storage made it particularly challenging to perform cross-cluster analytics and delayed the ability to identify network-wide patterns and trends.

The data processing architecture at Airties served two distinct use cases. The first was a traditional streaming pattern with a batch reader processing data in bulk for analytical purposes. The second use case used Kafka as a queryable data store—a pattern that, though unconventional, has become increasingly common in large-scale data architectures.

For this second use case, Airties needed to provide immediate access to historical device data when troubleshooting customer issues or analyzing specific network events. This was implemented by maintaining a mapping of data points to their Kafka offsets in a database. When customer support or analytics teams needed to retrieve specific historical data, they could quickly locate and fetch the exact records from high-retention Kafka topics using these stored offsets. This approach eliminated the need for a separate database system while maintaining fast access to historical data.

To handle the massive scale of operations, this solution was horizontally scaled across dozens of Kafka clusters, with each cluster responsible for managing approximately 25 TB of records.

The following diagram illustrates the previous Kafka-based architecture.

Challenges with the Kafka-based architecture

At Airties, managing and scaling Kafka clusters has presented several challenges, hindering the organization from focusing on delivering business value effectively:

  • Operational overhead: Maintaining and monitoring Kafka clusters requires significant manual effort and operational overhead at Airties. Tasks such as managing cluster upgrades, handling hardware failures and rotation, and conducting load testing constantly demand engineering attention. These operational tasks take away from the team’s ability to concentrate on core business functions and value-adding activities within the company.
  • Scaling complexities : The process of scaling Kafka clusters involves multiple manual steps that create operational burden for the cloud team. These include configuring new brokers, rebalancing partitions across nodes, and providing proper data distribution—all while maintaining system stability. As data volume and throughput requirements fluctuate, scaling typically involves adding or removing entire Kafka clusters, which is a complex and time-consuming process for the Airties team.
  • Right-sizing cluster capacity: The static nature of Kafka clusters created a “one-size-fits-none” situation for Airties. For large-scale deployments with high data volumes and throughput requirements, adding new clusters required significant manual work, including capacity planning, broker configuration, and partition rebalancing, making it inefficient for handling dynamic scaling needs. Conversely, for smaller deployments, the standard cluster size was oversized, leading to resource waste and unnecessary costs.

How the new architecture addresses these challenges

The Airties team needed to find a scalable, high-performance, and cost-effective solution for real-time data processing that would allow seamless scaling with increasing data volumes. Data durability was a critical requirement, because losing device telemetry data would create permanent gaps in customer analytics and historical troubleshooting capabilities. Although temporary delays in data access could be tolerated, the loss of any device data point was unacceptable for maintaining service quality and customer support effectiveness.

To address these challenges, Airties implemented two different approaches for different scenarios.

The primary use case was real-time data streaming with Kinesis Data Streams. Airties replaced Kafka with Kinesis Data Streams to handle the continuous ingestion and processing of telemetry data from tens of millions of endpoints. This shift offered significant advantages:

  • Auto-scaling capabilities : Kinesis Data Streams can be scaled through simple API calls, alleviating the need for complex configurations and manual interventions.
  • Stream isolation : Each stream operates independently, meaning scaling operations on one stream have no impact on others. This alleviated the risks associated with cluster-wide changes in their previous Kafka setup.
  • Dynamic shard management : Unlike Kafka, where changing the number of partitions requires creating a new topic, Kinesis Data Streams allows adding or removing shards dynamically without losing message ordering within a partition.
  • Application Auto Scaling: Airties implemented AWS Application Auto Scaling with Kinesis Data Streams, allowing the system to automatically adjust the number of shards based on actual usage patterns and throughput requirements.

These features empowered Airties to efficiently manage resources, optimizing costs during periods of lower activity while seamlessly scaling up to handle peak loads.

For providing on-demand access to historical device data, Airties implemented a decoupled architecture that separates streaming, storage, and data access concerns. This approach replaced the previous solution where historical data was stored directly in Kafka topics. The new architecture consists of several key components working together:

  • Data collection and processing : The architecture begins with a consumer application that processes data from Kinesis Data Streams. This application implements analyzing the data, as making it available for detailed historical analysis. The result of the data analysis is written to Amazon Data Firehose, which buffers the data, writing it regularly to Amazon Simple Storage Service (Amazon S3), where it can later be picked up by Amazon EMR. This path is optimized for efficient storage and bulk reading from Amazon S3 by Amazon EMR. For raw data storage, multiple raw data samples are batched together in bulk files, which are stored in a separate Amazon S3 path. This path is optimized for storage efficiency and fetching raw data using Amazon S3 range queries.
  • Indexing and metadata management: To enable fast data retrieval, the architecture implements a sophisticated indexing system. For each record in the uploaded bulk files, two crucial pieces of information are recorded in an Amazon DynamoDB table: the Amazon S3 location (bucket and key) where the bulk file was written, and the sequence number of the corresponding data record in the Kinesis Data Streams queue. This indexing strategy provides low-latency access to specific data points, efficient querying capabilities for both real-time and historical data, automatic scaling to handle increasing data volumes, and high availability for metadata lookups.
  • Ad-hoc data retrieval: When specific historical data needs to be accessed, the system follows an efficient retrieval process. First, the application queries the DynamoDB table using the relevant identifiers. The query returns the exact Amazon S3 location and offset where the required data is stored. The application then fetches the specific data directly from Amazon S3 using range queries. This approach enables quick access to historical data points, minimal data transfer costs by retrieving only needed records, efficient troubleshooting and analysis workflows, and reduced latency for customer support operations.

This decoupled architecture uses the strengths of each AWS service: Amazon Kinesis Data Streams provides scalable and reliable real-time data streaming, while Amazon S3 delivers durable and cost-effective object storage for raw data, and Amazon DynamoDB enables fast and flexible storage of metadata and indexing. By separating streaming from storage and utilizing each service for its specific strengths, Airties created a more cost-effective and scalable solution for ad-hoc data access needs, aligning each component with its optimal AWS service. The new architecture not only improved data access performance but also significantly reduced operational complexity. Instead of managing Kafka topics for historical data storage, Airties now benefits from fully managed AWS services that automatically handle scaling, durability, and availability. This approach has proven particularly valuable for customer support scenarios, where quick access to historical device data is crucial for resolving issues efficiently.

Solution overview

Airties’s new architecture involves several critical components, including efficient data ingestion, indexing with AWS Lambda functions, optimized data aggregation and processing, and comprehensive monitoring and management practices using Amazon CloudWatch. The following diagram illustrates this architecture.

The new architecture consists of the following key stages:

  • Data collection and storage: The data journey begins with Kinesis Data Streams, which ingests real-time data from millions of access points. This streaming data is then processed by a consumer application that batches the data into bulk files (also known as briefcase files) for efficient storage in Amazon S3. This approach of streaming, batching, and then storing minimizes write operations and reduces overall costs, while providing data durability through built-in replication in Amazon S3. When the data is in Amazon S3, it’s readily available for both immediate processing and long-term analysis. The processing pipeline continues with aggregators that read data from Amazon S3, process it, and store aggregated results back in Amazon S3. By integrating AWS Glue for ETL operations and Amazon Athena for SQL-based querying, Airties can process large volumes of data efficiently and generate insights quickly and cost-effectively.
  • Data aggregation and bulk file creation: The aggregators play a crucial role in the initial data processing. They aggregate the incoming data based on predefined criteria and create bulk files. This aggregation process reduces the volume of data that needs to be processed in subsequent steps, optimizing the overall data processing workflow. The aggregators then write these bulk files directly to Amazon S3.
  • Indexing: Upon successful upload of a bulk file to Amazon S3 by the aggregators, the aggregator will write an index entry for the bulk file an Amazon DynamoDB table. This indexing mechanism allows for efficient retrieval of data based on device IDs and timestamps, facilitating quick access to relevant data using S3 range queries on the bulk files.
  • Further processing and analysis: The bulk files stored in Amazon S3 are now in a format optimized for querying and analysis. These files can be further processed using AWS Glue and analyzed using Athena, allowing for complex queries and in-depth data exploration without the need for additional data transformation steps.
  • Monitoring and management: To maintain the reliability and performance of the Kafka-less architecture, comprehensive monitoring and management practices were implemented. CloudWatch provides real-time monitoring of system performance and resource utilization, allowing for proactive management of potential issues. Additionally, automated alerts and notifications make sure anomalies are promptly addressed.

Results and benefits

The transition to this new architecture yielded significant benefits for Airties:

  • Scalability and performance: The new architecture empowers Airties to scale seamlessly with increasing data volumes. The ability to independently scale reader and writer operations has reduced performance impacts during high-demand periods. This is a significant improvement over the previous Kafka-based system, where scaling often required complex reconfigurations and could affect the entire cluster. With Kinesis Data Streams, Airties can now handle peak loads effortlessly while optimizing resource usage during quieter periods.
  • Reliability and fault tolerance: By using AWS managed services, Airties has significantly reduced system latency and improved overall uptime. The automatic data replication and recovery processes of Kinesis Data Streams provide enhanced data durability, a critical requirement for Airties’s operations. The improved high availability means that Airties can now offer more reliable services to their customers, minimizing disruptions and enhancing the overall quality of their home connectivity solutions.
  • Operational efficiency: The new architecture has dramatically reduced the need for manual intervention in capacity management. This shift has freed up valuable engineering resources, allowing the team to focus on delivering business value rather than managing infrastructure. The simplified operational model has increased the team’s productivity, empowering them to innovate faster and respond more quickly to customer needs. The reduction in operational overhead has also led to faster deployment cycles and more frequent feature releases, enhancing Airties’s competitiveness in the market.
  • Environmental impact and sustainability: The transition to a serverless architecture demonstrated significant environmental benefits, achieving a remarkable 40% reduction in energy consumption. This substantial decrease in energy usage was achieved by eliminating the need for constantly running EC2 instances and using more efficient, managed AWS services. This improvement in energy efficiency aligns with Airties’s commitment to environmental sustainability and establishes them as an environmentally responsible leader in the tech industry.
  • Cost optimization: The financial benefits of transitioning to a Kafka-less architecture are clearly demonstrated through comprehensive AWS Cost Explorer data. As shown in the following diagram, the total cost breakdown across all relevant services from January to July includes EC2 instances, DynamoDB, other Amazon EC2 costs, Kinesis Data Streams, Amazon S3, and Amazon Data Firehose. The most notable change was a 33% reduction in total monthly infrastructure costs (compared to January baseline), primarily achieved through significant decrease in Amazon EC2 related costs as the migration progressed, elimination of dedicated Kafka infrastructure, and efficient use of the AWS pay-as-you-go model. Although new costs were introduced for managed services (DynamoDB, Kinesis Data Streams, Amazon Data Firehose, Amazon S3), the overall monthly AWS costs maintained a clear downward trend. With these cost savings, Airties can offer more competitive pricing to their customers. The diagram below shows monthly cost breakdown during the transition.

Conclusion

The transition to this new architecture with Kinesis Data Streams has marked a significant milestone in Airties’s journey towards operational excellence and sustainability. These initiatives have not only enhanced system performance and scalability, but have also resulted in substantial cost savings (33%) and energy efficiency (40%). By using advanced technologies and innovative solutions on AWS, the Airties team continues to set the benchmark for efficient, reliable, and sustainable operations, while paving the way for a sustainable future. In order to explore how you can modernize your streaming architecture with AWS, see the Kinesis Data Streams documentation and watch this re:invent session on serverless data streaming with Kinesis Data Streams and AWS Lambda.


About the Authors

Steven Aerts is a principal software engineer at Airties, where his team is responsible for ingesting, processing, and analyzing the data of tens of millions of homes to improve their Wi-Fi experience. He was a speaker at conferences like Devoxx and AWS Summit Dubai, and is an open source contributor.

Reza Radmehr is a Sr. Leader of Cloud Infrastructure and Operations at Airties, where he leads AWS infrastructure design, DevOps and SRE automation, and FinOps practices. He focuses on building scalable, cost-efficient, and reliable systems, driving operational excellence through smart, data-driven cloud strategies. He is passionate about blending financial insight with technical innovation to improve performance and efficiency at scale.

Ramazan Ginkaya is a Sr. Technical Account Manager at AWS with over 17 years of experience in IT, telecommunications, and cloud computing. He is a passionate problem-solver, providing technical guidance to AWS customers to help them achieve operational excellence and maximize the value of cloud computing.

Unlock self-serve streaming SQL with Amazon Managed Service for Apache Flink

Post Syndicated from Sofie Zilberman original https://aws.amazon.com/blogs/big-data/unlock-self-serve-streaming-sql-with-amazon-managed-service-for-apache-flink/

This post is co-written with Gal Krispel from Riskified.

Riskified is an ecommerce fraud prevention and risk management platform that helps businesses optimize online transactions by distinguishing legitimate customers from fraudulent ones.

Using artificial intelligence and machine learning (AI/ML), Riskified analyzes real-time transaction data to detect and prevent fraud while maximizing transaction approval rates. The platform provides a chargeback guarantee, protecting merchants from losses due to fraudulent transactions. Riskified’s solutions include account protection, policy abuse prevention, and chargeback management software, making it a comprehensive tool for reducing risk and enhancing customer experience. Businesses across various industries, including retail, travel, and digital goods, use Riskified to increase revenue while minimizing fraud-related losses. Riskified’s core business of real-time fraud prevention makes low-latency streaming technologies a fundamental part of its solution.

Businesses often can’t afford to wait for batch processing to make critical decisions. With real-time data streaming technologies like Apache Flink, Apache Spark, and Apache Kafka Streams, organizations can react instantly to emerging trends, detect anomalies, and enhance customer experiences. These technologies are powerful processing engines that perform analytical operations at scale. However, unlocking the full potential of streaming data often requires complex engineering efforts, limiting accessibility for analysts and business users.

Streaming pipelines are in high demand from Riskified’s Engineering department. Therefore, a user-friendly interface for creating streaming pipelines is a critical feature to increase analytical precision for detecting fraudulent transactions.

In this post, we present Riskified’s journey toward enabling self-service streaming SQL pipelines. We walk through the motivations behind the shift from Confluent ksqlDB to Apache Flink, the architecture Riskified built using Amazon Managed Service for Apache Flink, the technical challenges they faced, and the solutions that helped them make streaming accessible, scalable, and production-ready.

Using SQL to create streaming pipelines

Customers have a range of open source data processing technologies to choose from, such as Flink, Spark, ksqlDB, and RisingWave. Each platform offers a streaming API for data processing. SQL streaming jobs offer a powerful and intuitive way to process real-time data with minimal complexity. These pipelines use SQL, a widely known and declarative language, to perform real-time transformations, filtering, aggregations, and joins in continuous data streams.

To illustrate the power of streaming SQL in ecommerce fraud prevention, consider the concept of velocity checks, which are a critical fraud detection pattern. Velocity checks are a type of security measure used to detect unusual or rapid activity by monitoring the frequency and volume of specific actions within a given timeframe. These checks help identify potential fraud or abuse by analyzing repeated behaviors that deviate from normal user patterns. Common examples include detecting multiple transactions from the same IP address in a short time span, monitoring bursts of account creation attempts, or tracking the repeated use of a single payment method across different accounts.

Use case: Riskified’s velocity checks

Riskified implemented a real-time velocity check using streaming SQL to monitor purchasing behavior based on user identifier.

In this setup, transaction data is continuously streamed through a Kafka topic. Each message contains user agent information originating from the browser, along with the raw transaction data. Streaming SQL queries are used to aggregate the number of transactions originating from a single user identifier within short time windows.

For example, if the number of transactions from a given user identifier exceeds a certain threshold within a 10-second period, this might signal fraudulent activity. When that threshold is breached, the system can automatically flag or block the transactions before they are completed. The following figure and accompanying code provide a simplified example of the streaming SQL query used to detect this behavior.

Velocity check SQL flow

SELECT userIdentifier,TUMBLE_START(createdAt, INTERVAL '10' SECONDS) 
  AS windowStart,TUMBLE_END(createdAt, INTERVAL '10' SECONDS) 
  AS windowEnd, COUNT(*) AS paymentAttempts
FROM transactions
  WINDOW TUMBLING (SIZE 10 SECONDS)
GROUP BY userIdentifier;

Although defining SQL queries over static datasets might appear straightforward, developing and maintaining robust streaming applications introduces unique challenges. Traditional SQL operates on bounded datasets, which are finite collections of data stored in tables. In contrast, streaming SQL is designed to process continuous, unbounded data streams resembling the SQL syntax.

To address these challenges at scale and make streaming job creation accessible to engineering teams, Riskified implemented a self-serve solution based on Confluent ksqlDB, using its SQL interface and built-in Kafka integration. Engineers could define and deploy streaming pipelines using SQL, chaining ksqlDB streams from source to sink. The system supported both stateless and stateful processing directly on Kafka topics, with Avro schemas used to define the structure of streaming data.

Although ksqlDB provided a fast and approachable starting point, it eventually revealed several limitations. These included challenges with schema evolution, difficulties in managing compute resources, and the absence of an abstraction for managing pipelines as a cohesive unit. As a result, Riskified began exploring alternative technologies that could better support its expanding streaming use cases. The following sections outline these challenges in more detail.

Evolving the stream processing architecture

In evaluating alternatives, Riskified focused on technologies that could address the specific demands of fraud detection while preserving the simplicity that made the original approach appealing. The team encountered the following challenges in maintaining the previous solution:

  • Schemas are managed in Confluent Schema Registry, and the message format is Avro with FULL compatibility mode enforced. Schemas are constantly evolving according to business requirements. They are version controlled using Git with a strict continuous integration and continuous delivery (CI/CD) pipeline. As schemas grew more complex, ksqlDB’s approach to schema evolution didn’t automatically incorporate newly added fields. This behavior required dropping streams and recreating them to add new fields instead of just restarting the application to incorporate new fields. This approach caused inconsistencies with offset management due to the stream’s tear-down.
  • ksqlDB enforces a TopicNameStrategy schema registration strategy, which provides 1:1 schema-to-topic coupling. This means the exact schema definition has to be registered multiple times, one time for each topic it is used for. Riskified’s schema registry deployment uses RecordNameStrategy for schema registration. It’s an efficient schema registry strategy that allows for sharing schemas across multiple topics, storing fewer schemas, and reducing registry management overhead. Having mixed strategies in the schema registry caused errors with Kafka consumer clients attempting to decode messages, because the client implementation expected a RecordNameStrategy according to Riskified’s standard.
  • ksqlDB internally registers schema definitions in specific ways where fields are interpreted as nullable, and Avro Enum types are converted to Strings. This behavior caused deserialization errors when attempting to migrate native Kafka consumer applications to use the ksqlDB output topic. Riskified’s code base uses the Scala programming language, where optional fields in the schema are interpreted as Option. Transforming every field as optional in the schema definition required heavy refactoring, treating all Enum fields as Strings, and handling the Option data type for every field that requires safe handling. This cascading effect made the migration process more involved, requiring additional time and resources to achieve a smooth transition.

Managing resource contention in ksqlDB streaming workloads

ksqlDB queries are compiled into a Kafka Streams topology. The query definition defines the topology’s behavior.

Streaming query resources are shared rather than isolated. This approach typically leads to the overallocation of cluster resources. Its tasks are distributed across nodes in a ksqlDB cluster. This architecture means processing tasks with no resource isolation, and a specific task can impact other tasks running on the same node.

Resource contention between tasks on the same node is common in a production-intensive environment when using a cluster architecture solution. Operation teams often fine-tune cluster configurations to maintain acceptable performance, frequently mitigating issues by over-provisioning cluster nodes.

Challenges with ksqlDB pipelines

A ksqlDB pipeline is a chain of individual streams and lacks flow-level abstraction. Imagine a complex pipeline where a consumer publishes to multiple topics. In ksqlDB, each topic (both input and output) must be managed as a separate stream abstraction. However, there is no high-level abstraction to represent an entire pipeline that chains these streams together. As a result, engineering teams must manually assemble individual streams into a cohesive data flow, without built-in support for managing them as a single, complete pipeline.

This architectural approach particularly impacts operational tasks. Troubleshooting requires examining each stream separately, making it difficult to monitor and maintain pipelines that contain dozens of interconnected streams. When issues occur, the health of each stream needs to be checked individually, with no logical data flow component to help understand the relationships between streams or their role in the overall pipeline. The absence of a unified view of the data flow significantly increased operational complexity.

Flink as an alternative

Riskified began exploring alternatives for its streaming platform. The requirements were clear: a strong processing technology that combines a rich low-level API and a streaming SQL engine, backed by a strong open source community, proven to perform in the most demanding production environments.

Unlike the previous solution, which supported only Kafka-to-Kafka integration, Flink offers an array of connectors for various databases and Streaming platforms. It was quickly recognized that Flink had the potential to handle complex streaming use cases.

Flink offers multiple deployment options, including standalone clusters, native Kubernetes deployments using operators, and Hadoop YARN clusters. For enterprises seeking a fully managed option, cloud providers like AWS offer managed Flink services that help alleviate operational overhead, such as Managed Service for Apache Flink.

Benefits of using Managed Service for Apache Flink

Riskified decided to implement a solution using Managed Service for Apache Flink. This choice offered several key advantages:

  • It offers a quick and reliable way to run Flink applications and reduces the operational overhead of independently managing the infrastructure.
  • Managed Service for Apache Flink provides true job isolation by running each streaming application in its dedicated cluster. This means you can manage resources separately for each job and reduce the risk of heavy streaming jobs inflicting resource starvation for other running jobs.
  • It offers built-in monitoring using Amazon CloudWatch metrics, application state backup with managed snapshots, and automatic scaling.
  • AWS offers comprehensive documentation and practical examples to help accelerate the implementation process.

With these features, Riskified could focus on what truly matters—getting closer to the business goal and starting to write applications.

Using Flink’s streaming SQL engine

Developers can use Flink to build complex and scalable streaming applications, but Riskified saw it as more than just a tool for experts. They wanted to democratize the power of Flink into a tool for the entire organization, to solve complex business challenges involving real-time analytics requirements without needing a dedicated data professional.

To replace their previous solution, they envisioned maintaining a “build once, deploy many” application, which encapsulates the complexity of the Flink programming and allows the users to focus on the SQL processing logic.

Kafka was maintained as the input and output technology for the initial migration use case, which is similar to the ksqlDB setup. They designed a single, flexible Flink application where end-users can modify the input topics, SQL processing logic, and output destinations through runtime properties. Although ksqlDB primarily focuses on Kafka integration, Flink’s extensive connector ecosystem enables it to expand to diverse data sources and destinations in future phases.

Managed Service for Apache Flink provides a flexible way to configure streaming applications without modifying their code. By using runtime parameters, you can change the application’s behavior without modifying its source code.

Using Managed Service for Apache Flink for this approach includes the following steps:

  1. Apply parameters for the input/output Kafka topic, a SQL query, and the input/output schema ID (assuming you’re using Confluent Schema Registry).
  2. Use AvroSchemaConverter to convert an Avro schema into a Flink table.
  3. Apply the SQL processing logic and save the output as a view.
  4. Sink the view results into Kafka.

The following diagram illustrates this workflow.
Streaming SQL system diagram

Performing Flink SQL query compilation without a Flink runtime environment

Providing end-users with significant control to define their pipelines makes it critical to verify the SQL query defined by the user before deployment. This validation prevents failed or hanging jobs that could consume unnecessary resources and incur unnecessary costs.

A key challenge was validating Flink SQL queries without deploying the full Flink runtime. After investigating Flink’s SQL implementation, Riskified discovered its dependency on Apache Calcite – a dynamic data management framework that handles SQL parsing, optimization, and query planning independently of data storage. This insight enabled using Calcite directly for query validation before job deployment.

You must know how the data is structured to validate a Flink SQL query on a streaming source like a Kafka topic. Otherwise, unexpected errors might occur when attempting to query the streaming source. Although an expected schema is used with relational databases, it’s not enforced for streaming sources.

Schemas guarantee a deterministic structure for the data stored in a Kafka topic when using a schema registry. A schema can be materialized into a Calcite table that defines how data is structured in the Kafka topic. It allows inferring table structures directly from schemas (in this case, Avro format was used), enabling thorough field-level validation, including type checking and field existence, all before job deployment. This table can later be used to validate the SQL query.

The following code is an example of supporting basic field types validation using Calcite’s AbstractTable:

public class FlinkValidator {
    public static void validateSQL(String sqlQuery, Schema avroSchema) throws Exception {
        SqlParser.Config sqlConfig = SqlParser.config()
                .withCaseSensitive(true);
        SqlParser sqlParser = SqlParser.create(sqlQuery, sqlConfig);
        SqlNode parsedQuery = sqlParser.parseQuery();
        RelDataTypeFactory typeFactory = new SqlTypeFactoryImpl(RelDataTypeFactory.DEFAULT);
        CalciteSchema rootSchema = createSchemaWithAvro(avroSchema);
        SqlValidator validator = SqlValidatorUtil.newValidator(
                Frameworks.newConfigBuilder().build().getOperatorTable(),
                rootSchema.createCatalogReader(Collections.emptyList(), typeFactory),
                typeFactory,
                SqlValidator.Config.DEFAULT
        );
        validator.validate(parsedQuery);
    }
    private static CalciteSchema createSchemaWithAvro(Schema avroSchema) {
        CalciteSchema rootSchema = CalciteSchema.createRootSchema(true);
        rootSchema.add("TABLE", new SimpleAvroTable(avroSchema));
        return rootSchema;
    }
    private static class SimpleAvroTable extends org.apache.calcite.schema.impl.AbstractTable {
        private final Schema avroSchema;
        public SimpleAvroTable(Schema avroSchema) {
            this.avroSchema = avroSchema;
        }
        @Override
        public RelDataType getRowType(RelDataTypeFactory typeFactory) {
            RelDataTypeFactory.Builder builder = typeFactory.builder();
            for (Schema.Field field : avroSchema.getFields()) {
                builder.add(field.name(), convertAvroType(field.schema(), typeFactory));
            }
            return builder.build();
        }
        private RelDataType convertAvroType(Schema schema, RelDataTypeFactory typeFactory) {
            switch (schema.getType()) {
                case STRING:
                    return typeFactory.createSqlType(SqlTypeName.VARCHAR);
                case INT:
                    return typeFactory.createSqlType(SqlTypeName.INTEGER);
                default:
                    return typeFactory.createSqlType(SqlTypeName.ANY);
            }
        }
    }
}

You can integrate this validation approach as an intermediate step before creating the application. You can create a streaming job programmatically with the AWS SDK, AWS Command Line Interface (AWS CLI), or Terraform. The validation occurs before submitting the streaming job.

Flink SQL and Confluent Avro data type mapping limitation

Flink provides several APIs designed for different levels of abstraction and user expertise:

  • Flink SQL sits at the highest level, allowing users to express data transformations using familiar SQL syntax, which is ideal for analysts and teams comfortable with relational concepts.
  • The Table API offers a similar approach but is embedded in Java or Python, enabling type-safe and more programmatic expressions.
  • For more control, the DataStream API exposes low-level constructs to manage event time, stateful operations, and complex event processing.
  • At the most granular level, the ProcessFunction API provides full access to Flink’s runtime features. It’s suitable for advanced use cases that demand detailed control over state and processing behavior.

Riskified initially used the Table API to define streaming transformations. However, when deploying their first Flink job to a staging environment, they encountered serialization errors related to the avro-confluent library and Table API. Riskified’s schemas rely heavily on Avro Enum types, which the avro-confluent integration doesn’t fully support. As a result, Enum fields were converted to Strings, leading to mismatches during serialization and errors when attempting to sink processed data back to Kafka using Flink’s Table API.

Riskified developed an alternative approach to overcome the Enum serialization limitations while maintaining schema requirements. They discovered that Flink’s DataStream API could correctly handle Confluent’s Avro records serialization with Enum fields, unlike the Table API. They implemented a hybrid solution combining both APIs because the pipeline only required SQL processing on the source Kafka topic. It can sink to the output without any additional processing. The Table API is used for data processing and transformations, only converting to the DataStream API at the final output stage.

Managed Service for Apache Flink supports Flink APIs. It can switch between the Table API and the DataStream API.
A MapFunction can convert the Row type of the Table API into a DataStream of GenericRecord. The MapFunction maps Flink’s Row data type into GenericRecord types by iterating over the Avro schema fields and building the GenericRecord from the Flink Row type, casting the Row fields into the correct data type according to the Avro schema. This conversion is required to overcome the avro-confluent library limitation with Flink SQL.

The following diagram and illustrates this workflow.

Flink Table and DataStream APIs

The following code is an example query:

// SQL Query for filtering
Table queryResults = tableEnv.sqlQuery(
       "SELECT * FROM InputTable");
// 1. Convert query results from Table API to a DataStream<Row> and use DataStream API to sink query results to Kafka topic
DataStream<Row> rowStream = tableEnv.toDataStream(queryResults);
// Fetch the schema string from the schema registry
String schemaString = fetchSchemaString(schemaRegistryURL, schemaSubjectName);
// 2. Convert Row to GenericRecord with explicit TypeInformation, using custom AvroMapper
TypeInformation<GenericRecord> typeInfo = new GenericRecordAvroTypeInfo(avroSchema);
DataStream<GenericRecord> genericRecordStream = rowStream
       .map(new AvroMapper(schemaString))
       .returns(typeInfo); // Explicitly set TypeInformation
// 3. Define Kafka sink using ConfluentRegistryAvroSerializationSchema
KafkaSink<GenericRecord> kafkaSink = KafkaSink.<GenericRecord>builder()
       .setBootstrapServers(bootstrapServers)
       .setRecordSerializer(
               KafkaRecordSerializationSchema.builder()
                       .setTopic(sinkTopic)
                       .setValueSerializationSchema(
                               ConfluentRegistryAvroSerializationSchema.forGeneric(
                                       schemaSubjectName,
                                       avroSchema,
                                       schemaRegistryURL
                               )
                       )
                       .build()
       )
       .build();
// Sink to Kafka
genericRecordStream.sinkTo(kafkaSink);

CI/CD With Managed Service for Apache Flink

With Managed Service for Apache Flink, you can run a job by selecting an Amazon Simple Storage Service (Amazon S3) key containing the application JAR. Riskified’s Flink code base was structured as a multi-module repository to support additional use cases besides supporting self-service SQL. Each Flink job source code in the repository is an independent Java module. The CI pipeline implemented a robust build and deployment process consisting of the following steps:

  1. Build and compile each module.
  2. Run tests.
  3. Package the modules.
  4. Upload the artifact to the artifacts bucket twice: one JAR under <module>-<version>.jar and the second as <module>-latest.jar, resembling a Docker registry like Amazon Elastic Container Registry (Amazon ECR). Managed Service for Apache Flink jobs uses the latest tag artifact in this case. However, a copy of old artifacts is kept for code rollback reasons.

A CD process follows this process:

  1. When merged, it lists all jobs for each module using the AWS CLI for Managed Service for Apache Flink.
  2. The application JAR location is updated for each application, which triggers a deployment.
  3. When the application is in a running state with no errors, the following application will be continued.

To allow safe deployment, this process is done gradually for every environment, starting with the staging environment.

Self-service interface for submitting SQL jobs

Riskified believes an intuitive UI is crucial for system adoption and efficiency. However, developing a dedicated UI for Flink job submission requires a pragmatic approach, because it might not be worth investing in unless there’s already a web interface for internal development operations.

Investing in UI development should align with the organization’s existing tools and workflows. Riskified had an internal web portal for similar operations, which made the addition of Flink job submission capabilities a natural extension of the self-service infrastructure.

An AWS SDK was installed on the web server to allow interaction with AWS components. The client receives user input from the UI and translates it into runtime properties to adjust the behavior of the Flink application. The web server then uses the CreateApplication API action to submit the job to Managed Service for Apache Flink.

Although an intuitive UI significantly enhances system adoption, it’s not the only path to accessibility. Alternatively, a well-designed CLI tool or REST API endpoint can provide the same self-service capabilities.

The following diagram illustrates this workflow.

Flow sequence diagram

Production experience: Flink’s implementation upsides

The transition to Flink and Managed Service for Apache Flink proved efficient in numerous aspects:

  • Schema evolution and data handling – Riskified can either periodically fetch updated schemas or restart applications when schemas evolve. They can use existing schemas without self-registration.
  • Resource isolation and management – Managed Service for Apache Flink runs each Flink job as an isolated cluster, reducing resource contention between jobs.
  • Resource allocation and cost-efficiency – Managed Service for Apache Flink enables minimum resource allocation with automatic scaling, proving to be more cost-efficient.
  • Job management and flow visibility – Flink provides a cohesive data flow abstraction through its job and task model. It manages the entire data flow in a single job and distributes the workload evenly over multiple nodes. This unified approach enables better visibility into the entire data pipeline, simplifying monitoring, troubleshooting, and optimizing complex streaming workflows.
  • Built-in recovery mechanism – Managed Service for Apache Flink automatically creates checkpoints and savepoints that enable stateful Flink applications to recover from failures and resume processing without data loss. With this feature, streaming jobs are durable and can recover safely from errors.
  • Comprehensive observability – Managed Service for Apache Flink exposes CloudWatch metrics that monitor Flink application performance and statistics. You can also create alarms based on these metrics. Riskfied decided to use the Cloudwatch Prometheus Exporter to export these metrics to Prometheus and build PrometheusRules to align Flink’s monitoring to the Riskified standard, which uses Prometheus and Grafana for monitoring and alerting.

Next steps

Although the initial focus was Kafka-to-Kafka streaming queries, Flink’s wide range of sink connectors offers the possibility of pluggable multi-destination pipelines. This versatility is on Riskfied’s roadmap for future enhancements.

Flink’s DataStream API provides capabilities that extend far beyond self-serving streaming SQL capabilities, opening new avenues for more sophisticated fraud detection use cases. Riskified is exploring ways to use DataStream APIs to enhance ecommerce fraud prevention strategies.

Conclusions

In this post, we shared how Riskified successfully transitioned from ksqlDB to Managed Service for Apache Flink for its self-serve streaming SQL engine. This move addressed key challenges like schema evolution, resource isolation, and pipeline management. Managed Service for Apache Flink offers features such as including isolated jobs environments, automatic scaling, and built-in monitoring, which proved more efficient and cost-effective. Although Flink SQL limitations with Kafka required workarounds, using Flink’s DataStream API and user-defined functions resolved these issues. The transition has paved the way for future expansion with multi-targets and advanced fraud detection capabilities, solidifying Flink as a robust and scalable solution for Riskified’s streaming needs.

If Riskified’s journey has sparked your interest in building a self-service streaming SQL platform, here’s how to get started:


About the authors

Gal Krispel is a Data Platform Engineer at Riskified, specializing in streaming technologies such as Apache Kafka and Apache Flink. He focuses on building scalable, real-time data pipelines that power Riskified’s core products. Gal is particularly interested in making complex data architectures accessible and efficient across the organization. His work spans real-time analytics, event-driven design, and the seamless integration of stream processing into large-scale production systems.

Sofia ZilbermanSofia Zilberman works as a Senior Streaming Solutions Architect at AWS, helping customers design and optimize real-time data pipelines using open-source technologies like Apache Flink, Kafka, and Apache Iceberg. With experience in both streaming and batch data processing, she focuses on making data workflows efficient, observable, and high-performing.

Lorenzo NicoraLorenzo Nicora works as Senior Streaming Solution Architect at AWS, helping customers across EMEA. He has been building cloud-centered, data-intensive systems for over 25 years, working across industries both through consultancies and product companies. He has used open-source technologies extensively and contributed to several projects, including Apache Flink, and is the maintainer of the Flink Prometheus connector.

Transforming Maya’s API management with Amazon API Gateway

Post Syndicated from Arthi Jaganathan original https://aws.amazon.com/blogs/architecture/transforming-mayas-api-management-with-amazon-api-gateway/

In this post, you will learn how Amazon Web Services (AWS) customer, Maya, the Philippines’ leading fintech company and digital bank, built an API management platform to address the growing complexities of managing multiple APIs hosted on Amazon API Gateway. API Gateway is a fully managed service that you can use to create RESTful and WebSocket APIs.

At Maya, different teams build APIs to expose their services to merchants. As the number of applications grew, the overhead of managing APIs increased. An API platform is a set of tools to simplify and standardize across API management concerns such as security, governance, automated deployments, observability, and integrations with multiple AWS accounts. This frees up application teams to focus on features while offloading management concerns to the API platform.

Initial state

Prior to implementing the API platform, Maya used a decentralized API management approach, which created significant challenges. Individual teams operated independent API gateways, resulting in fragmented infrastructure, leading to several issues:

  1. Lack of standardization: Implementing consistent API standards across the organization proved difficult. Each team maintained its own configurations and practices, leading to inconsistencies in security and documentation.
  2. Security posture maintenance: While Maya maintained a strong security posture, doing so across the numerous independent gateways was unsustainable. The overhead of applying consistent security policies and updates across all gateways was becoming increasingly burdensome.
  3. Inconsistent operational visibility: Observability wasn’t inherently limited, rather inconsistently applied. Having multiple, different gateways makes it challenging to enforce a unified observability strategy and correlate data across the entire API ecosystem.

Solution overview

To address these challenges, Maya implemented an API platform, code-named Unified API Gateway. This centralized API management helps enforce consistent standards and improve overall security and observability. The following image illustrates the architecture of the Unified API Gateway and how it integrates with backend services managed and owned by different teams across different AWS accounts.

Enterprise-level AWS architecture diagram showing secured API gateway with multi-account EKS service distribution

API Platform Architecture

Maya chose to host all APIs in a central API account to centralize governance. This is managed by a dedicated shared services cloud team. Amazon CloudFront with AWS WAF and AWS Shield Advanced integration provides perimeter security. An AWS Lambda authorizer provides application security by managing authentication, authorization, and session management. This mitigates against the OWASP top 10 API security risks.

Integration to backend services is configured through API Gateway private integration and AWS Transit Gateway. In a decentralized API deployment strategy where APIs are co-hosted with the service in the respective AWS account, the integration will be simpler because you won’t need cross-account network connectivity. You will still benefit from the API management techniques covered in this post.

Standardization through structured service on-boarding

OpenAPI Specification (OAS) provides a structured definition for APIs. As shown in the following figure, service teams define the API OAS specification. This is embedded in Terraform infrastructure-as-code template for API Gateway. These are checked into source code repository and deployed using GitLab CI.

End-to-end API infrastructure pipeline showing specification integration through GitLab CI to AWS API Gateway

API Gateway Infrastructure-as-code (IaC) Pipeline

A configuration file used as a Terraform template supplies parameters for components of the solution such as backend integration, Lambda authorizer details, and additional headers for auditing. The following OAS snippets demonstrate this.

  1. Integration with the backend service
    x-amazon-apigateway-integration:
       type: "http_proxy"
       connectionId: "${vpc_link_id}"
       httpMethod: "GET"
       uri: "http://$${stageVariables.url}:11620/v1/api/endpoint/{id}" # double $ is not a typo
  2. Adding headers to the request
    x-amazon-apigateway-integration:
       type: "http_proxy"
       connectionId: "${vpc_link_id}"
       httpMethod: "GET"
       uri: "http://$${stageVariables.url}:11620/v1/api/endpoint/{id}"
       requestParameters:
          integration.request.header.x-requesting-service-id: "'api-gw'"
          integration.request.header.x-org-customer-id: "context.authorizer.x-org-customer-id"
  3. Security definition
    securitySchemes:
       lambda-authorizer:
          type: "${authorizer_type}"  
          name: "${authorizer_name}"
          x-amazon-apigateway-authtype: "custom"
          x-amazon-apigateway-authorizer:
             type: "request"
             authorizerUri: "${authorizer_uri}"
             authorizerCredentials: "${authorizer_credentials}"
             identitySource: "${authorizer_identity_source}"

API Gateway supports most of the OpenAPI 2.0 specification and the OpenAPI 3.0 specification but there are a few exceptions. Maya uses a custom plugin in the pipeline to enforce necessary limiting rules to help ensure compatibility with API Gateway.

To simplify deployment for development teams, a custom Terraform module abstracts away the API Gateway implementation details.

module "test-microservice-api-gateway" {
  # module version parameters
  source = "gitlabinstance.com/platform-engineering/apigw-terraform-module/aws"
  version = "1.2.7"

  # module deployed infrastructure parameters
  api_name = var.api_name
  api_mapping_path = var.api_mapping_path
  environment = var.environment
  aws_region = var.aws_region
  account_id = var.account_id
  tags = var.tags
  domain_name = var.domain_name
  stage_name = var.stage_name

  oas_path = var.oas_path # this value is populated via environment variable in Gitlab CI/CD

  providers = {
     aws = aws.apigw
  }
  authorizer_credentials = var.authorizer_credentials
  authorizer_uri = var.authorizer_uri
  vpc_link_id = var.vpc_link_id
  endpoint_url = var.endpoint_url
}

To use multi-level prefixes for custom domains with REST API Gateway, you need the Terraform module for API Gateway v2.

resource "aws_api_gateway_rest_api" "apigw" {
   name = "${var.environment}-${var.api_name}"
   body = templatefile(
     local.oasFilePath,
     {
       vpc_link_id = var.vpc_link_id
       authorizer_uri = var.authorizer_uri
       authorizer_credentials = var.authorizer_credentials
     }
  )
  description = "API Gateway for ${var.api_name}"
  endpoint_configuration {
    types = ["REGIONAL"]
  }

   # Default endpoint needs to be disabled if CloudFront is used as entry point to API Gateway
  disable_execute_api_endpoint = true
  tags = local.tags
  }

  # Use apigatewayv2 in order to have multi level base path ex. /v1/service_name
  resource "aws_apigatewayv2_api_mapping" "this" {
     domain_name = var.domain_name
    api_id = aws_api_gateway_rest_api.apigw.id
    stage = aws_api_gateway_stage.apigw.stage_name
    api_mapping_key = var.api_mapping_path
  }

Simplify API security with automation

Maya’s Unified API Gateway implements a robust, multi-layered security strategy. This approach helps ensure comprehensive protection from external threats and enforces stringent access control policies.

AWS WAF inspects and filters incoming traffic to protect against common web exploits, including OWASP Top 10, such as SQL injection and cross-site scripting attacks. A combination of custom and managed rule sets blocks malicious requests and enforces security policies. AWS Shield Advanced mitigates distributed denial of service (DDoS) attacks and provides 24/7 access to the AWS Shield Response Team (SRT) for expert support during attack events. This helps ensure high availability and resiliency.

API Gateway is integrated with a Lambda authorizer for authentication and authorization. The custom function implements fine-grained access control based on several factors such as identity, roles, and scopes.

To help ensure the consistency and integrity of the API configurations, all updates and deployments are strictly managed through an automated infrastructure-as-code (IaC) pipeline. This helps eliminate the risk of unauthorized or accidental manual changes to the API Gateway and any underlying infrastructure. The IaC pipeline makes sure that all API configurations, including security settings, are deployed through a controlled and auditable process. This prevents configuration drift and makes sure that security policies are consistently applied across all APIs. This also means that all changes are subject to code reviews and version control, adding another layer of security and traceability.

End-to-end visibility with observability

Maya’s Unified API Gateway prioritizes comprehensive observability to proactively monitor API performance, identify potential issues, and provide a seamless user experience. It uses a combination of AWS services and integrated tools to achieve this.

Amazon CloudWatch is used to monitor key performance metrics, including latency, error rates, and requests counts. CloudWatch provides real-time insights into the health and performance of APIs. Alerts on P95 and P99 values help identify and address performance bottlenecks, ensuring responsiveness.

CloudWatch metrics are streamed to Dynatrace, an application performance monitoring (APM) tool. The centralized view helps correlate data from various sources, create custom dashboards, and configure intelligent alerts based on predefined thresholds.

To help ensure complete visibility into API activity, the Lambda authorizer and API Gateway access logs are centralized in Splunk. This provides a comprehensive audit trail to track authentication and authorization events, identify security incidents, and troubleshoot API requests. Headers generated after authentication and authorization are done are passed down to the backend services for proper log correlation.

Future roadmap

The Unified API Gateway will continue to evolve to meet the growing needs of the organization and its partners and customers. The following are the key future enhancements that will further streamline API management, improve the developer experience, and enhance security.

  1. Integration with the internal developer portal: This will provide a self-service UI for bootstrapping new APIs from scratch and further empower developers. This will also simplify documentation and discovery by cataloging all APIs
  2. A modular, extension-based design for enhanced processing: This will introduce custom processing of requests in-line in the gateway account before integrating with backend services. Examples include digital signature verification, message transformation, and custom business logic. A modular design will offer a flexible and scalable way to enhance the functionality of Maya’s APIs without modifying backend services.
  3. Bring your own (BYO) authorizer: Support a wider range of identity providers and authentication protocols, providing greater flexibility and control over API access.
  4. Centralizing schema validation: Moving schema validation to API Gateway to bring consistency and improve the robustness and security of APIs by preventing malformed or malicious requests from being processed.
  5. API monetization: Create new revenue streams by adding support for usage-based billing, tiered pricing, and subscription models.

Conclusion

This post has described the creation of Maya’s robust API management and governance solution, using a combination of native AWS services and powerful partner tools such as Terraform and Dynatrace. We’ve demonstrated how this Unified API Gateway has streamlined and automated core API processes, transforming Maya’s previously fragmented infrastructure into a secure and observable ecosystem. By establishing clear guardrails, the API solution team empowers developers to rapidly deploy APIs while maintaining consistent standards.

With the recent implementation of this solution across more teams, Maya is focused on defining and tracking key performance indicators (KPIs). We anticipate measuring critical metrics such as API onboarding efficiency, developer experience, API latency, and security incident rates. These insights will serve as a foundation for continuous improvement and optimization, ensuring the solution’s sustained effectiveness and evolution.

Visit the API platform guidance on Serverlessland to learn more about building API platforms. See the API Gateway pattern collection to learn more about designing REST API integrations on AWS.


About the Authors

How Smartsheet boosts developer productivity with Amazon Bedrock and Roo Code

Post Syndicated from Rony Blum original https://aws.amazon.com/blogs/architecture/how-smartsheet-boosts-developer-productivity-with-amazon-bedrock-and-roo-code/

This post was co-written with JB Brown from Smartsheet.

Organizations are often seeking ways to enhance developer productivity while maintaining cost-efficiency. AI-powered coding assistants are effective solutions to accelerate development cycles, but implementing these solutions at scale while managing costs presents unique challenges. Roo Code, an AI-powered autonomous coding agent located directly in developers’ editors, represents the latest evolution in AI-assisted development. It helps developers code faster and smarter by offering capabilities ranging from code generation and refactoring to documentation writing and code base analysis through natural language interaction. This post explores how Smartsheet successfully deployed Roo Code with Amazon Bedrock and Anthropic’s Claude, achieving significant improvements in developer efficiency while optimizing costs through innovative caching strategies.

The Amazon Bedrock prompt caching capability, which became generally available in April 2025, represents a significant advancement in optimizing AI model interactions. With this feature, organizations can cache frequently used prompts across multiple API calls, reducing costs by up to 90% and lowing latency by up to 85%. The technology is particularly valuable for applications that repeatedly use similar context, such as coding assistants that need to maintain context about code files. Prompt caching supports multiple foundation models (FMs), including Anthropic’s Claude 3.5 Haiku and Anthropic’s Claude 3.7 Sonnet, as well as the Amazon Nova family of models. The cached context remains available for up to 5 minutes after each access, with each cache hit resetting this countdown. For organizations implementing AI-assisted development workflows, they can use this capability to balance performance with cost-efficiency.

Benefits of Amazon Bedrock prompt caching

Smartsheet is a leading cloud-based enterprise work management service, enabling millions of users worldwide to plan, manage, track, automate, and report on work at scale. Their engineering team identified an opportunity to enhance developer productivity by implementing AI-assisted coding capabilities across their organization. The solution needed to scale efficiently while maintaining reasonable costs, leading them to choose Roo Code with Amazon Bedrock with Anthropic’s Claude as their FM provider.

“Our engineering team has achieved a 60% reduction in operational costs and 20% improvement in response latency when using Roo Code with Amazon Bedrock prompt caching. These improvements directly translate to enhanced developer productivity across our organization,” says JB Brown, VP of Engineering at Smartsheet.

This fact is underscored by the team’s ability to rapidly generate comprehensive code documentation and architecture diagrams in a mere four hours, a task that previously consumed 2 weeks of manual effort. This newfound efficiency extends to critical areas like AWS cost management, where a vital analysis tool was built in just 30 minutes, and is projected to save Smartsheet $450,000 annually. Furthermore, the speed and accessibility of information have been significantly amplified, as evidenced by the 6–8 hours of senior engineer time saved by quickly explaining complex Terraform/Terragrunt infrastructure. These examples highlight how Amazon Bedrock prompt caching is not just about incremental gains, but about unlocking substantial time and resource savings, empowering our developers to focus on innovation rather than time-consuming manual processes.

Solution overview

When implementing AI-assisted coding at scale, Smartsheet faced several key challenges around managing costs associated with large language model (LLM) API calls, reducing latency for developer interactions and handling repetitive elements in prompts efficiently. The development team recognized that a significant portion of the prompts sent to Amazon Bedrock were repeated elements: the system prompt and the continuously building message history, presenting an opportunity for optimization.

To address these challenges, Smartsheet implemented a comprehensive solution centered around Roo Code integration with Amazon Bedrock and prompt caching. Smartsheet deployed Roo Code, powered by Amazon Bedrock and Anthropic’s Claude 3.7, across the organization and integrated seamlessly into existing development workflows. This provided developers with immediate access to AI assistance for code writing, reviewing, and debugging tasks.

The team then contributed a sophisticated Amazon Bedrock prompt caching system to Roo Code that identifies and stores common prompt elements, significantly reducing redundant data transmission to Bedrock. This caching layer proved crucial in optimizing both cost and performance metrics. The caching decision flow incorporates two key checks: first, it verifies if the selected model supports prompt caching, then it makes sure the system prompt meets a minimum token threshold to make caching worthwhile.

The solution integrates Roo Code directly into developers’ integrated development environments (IDE), using the Amazon Bedrock prompt caching capabilities. The architecture separates content into static elements (like system instructions and code context) and dynamic elements (like user queries). When a developer makes a request, static content is automatically marked with cache checkpoints and stored for 5 minutes, with each access refreshing this window.

For subsequent queries, the system checks for matching cached content before processing. When matches are found, it bypasses recomputation of these sections, significantly reducing both response time and costs.

The following diagram shows the integration points between Roo Code and Amazon Bedrock.

Technical workflow diagram showing data flow between user query, cache decision logic, and Amazon Bedrock with response handling

The following screenshot highlights the model provider settings and connection parameters required for implementation.

Amazon Bedrock configuration interface showing AWS authentication, region settings, and Claude model with caching enabled

Optimizing performance with prompt caching

When analyzing code files, much of the context—such as file contents and environment details—remains consistent across multiple queries. By caching this content, subsequent requests can reuse it from the cache, significantly reducing cost and latency.

In our example, we first asked Roo Code to analyze a Python file. We then sent multiple follow-up queries about different aspects of the code. The first query explained the overall structure, followed by questions about specific classes, unused modules, and potential improvements.

The usage section of the responses showed significant improvements through caching. During the first query, the model processed the input and wrote the cached content. For subsequent queries, 90% of the input was served from the cache. Because cache reads are 90% cheaper than processing new input tokens, this resulted in an 83% cost reduction for follow-up queries.

Here’s how the caching worked across queries:

  • First query – The model processed the entire file content and environment details, writing them to cache
  • Subsequent queries – The model loaded the cached content, only processing the new question text

To illustrate this, let’s look at the usage statistics from a series of queries:

Query 1: "Explain my @/src/models/product.py code"
{
    "inputTokens": 1051,
    "outputTokens": 902,
    "totalTokens": 19374,
    "cacheReadInputTokenCount": 0,
    "cacheWriteInputTokenCount": 12421
}

Query 2: "Describe what is ProductUpdate class used for"
{
    "inputTokens": 1078,
    "outputTokens": 694,
    "totalTokens": 21664,
    "cacheReadInputTokenCount": 19892,
    "cacheWriteInputTokenCount": 0
}

Query 3: "Which module is not in use?"
{
    "inputTokens": 4,
    "outputTokens": 774,
    "totalTokens": 22753,
    "cacheReadInputTokenCount": 19892,
    "cacheWriteInputTokenCount": 2083
}

Query 4: "Any improvement to implement to my code making it more efficient?"
{
    "inputTokens": 1097,
    "outputTokens": 1270,
    "totalTokens": 24342,
    "cacheReadInputTokenCount": 21975,
    "cacheWriteInputTokenCount": 0
} 

We can see from the results that the first query didn’t return cacheReadInputTokenCount but wrote to the cache the whole input. For subsequent queries, most of the input was read from the cache, except for the specific question.

The results clearly demonstrate the benefits of prompt caching:

  • 70% of total input was served from cache across queries
  • 90% of input for follow-up queries came from cache
  • Overall input costs reduced by 60%
  • Follow-up query costs reduced by 83%

This approach is particularly effective for development workflows where developers frequently query the same code base with different questions. The cached content provides necessary context for each query while significantly reducing processing overhead.

The following screenshot displays Roo Code’s interface, showing detailed metrics including token usage, cache hit rates, and associated API costs. The interface presents the cost savings achieved through caching and provides comprehensive usage analytics.

IDE showing Roo Code analysis with metrics, API costs, and detailed Python code explanation

Results and future innovation

The following line graph demonstrates the cost reduction trend over multiple queries runs, having the first query uncached, and the subsequent input using significant query responses from the cache. The y-axis shows costs in dollars, and the x-axis shows the cost per query. The graph shows a clear downward trend, with costs decreasing by 60% from the baseline.

Dual-axis graph displaying per-query and cumulative costs, demonstrating cost savings through caching over 4 queries

The implementation delivered remarkable improvements across key metrics. The prompt caching system achieved a 60% reduction in operational costs while simultaneously improving response latency by 20%.

The choice of Amazon Bedrock prompt caching proved particularly effective for Smartsheet’s coding assistance workflows. The 5-minute cache Time to Live (TTL) aligns perfectly with the natural rhythm of developer interactions with Roo Code, where multiple related queries typically occur within short timeframes. During active coding sessions, developers engage in rapid back-and-forth exchanges with the AI assistant—reviewing code, asking follow-up questions, and requesting modifications—while maintaining context through the cache. This agentic workflow, where each interaction builds upon previous context, takes full advantage of the prompt caching mechanism—each query refreshes the cache timer while preserving valuable context about the code being discussed.

Best practices and lessons learned

Through their implementation journey, Smartsheet developed several key best practices for organizations looking to implement similar solutions. Early implementation of prompt caching proved crucial, allowing the team to analyze prompt patterns and design efficient caching strategies from the start. The team found that focusing on developer experience through response time optimization and seamless tool integration was essential for successful adoption.

Continuous monitoring and analysis of usage patterns became a cornerstone of their optimization strategy. By tracking key metrics like response times and costs, the team could identify opportunities for further optimization and regularly adjust their caching strategies to maintain optimal performance.

Looking ahead

Smartsheet continues to innovate with Amazon Bedrock and Roo Code, exploring new ways to enhance developer productivity. Their engineering team is investigating advanced caching strategies and evaluating new FMs as they become available on Amazon Bedrock. The success of this implementation has established a strong foundation for future AI-assisted development initiatives.

Conclusion

Smartsheet’s implementation of Roo Code with Amazon Bedrock and prompt caching demonstrates how organizations can successfully deploy AI-assisted coding solutions while maintaining cost-efficiency. Their approach provides a blueprint for others looking to enhance developer productivity through AI while optimizing operational costs. The combination of strategic implementation, innovative caching solutions, and continuous optimization has enabled Smartsheet to achieve significant improvements in performance and cost metrics.

To learn more about implementing AI solutions at scale, refer to the Amazon Bedrock documentation and explore the AWS Machine Learning Blog. The frameworks and strategies outlined in this post can help organizations of varying size implement efficient, cost-effective AI-assisted development workflows.


About the Authors

How LaunchDarkly migrated to Amazon MWAA to achieve efficiency and scale

Post Syndicated from Asena Uyar, Dean Verhey original https://aws.amazon.com/blogs/big-data/how-launchdarkly-migrated-to-amazon-mwaa-to-achieve-efficiency-and-scale/

This is a guest post coauthored with LaunchDarkly.

The LaunchDarkly feature management platform equips software teams to proactively reduce the risk of shipping bad software and AI applications while accelerating their release velocity. In this post, we explore how LaunchDarkly scaled the internal analytics platform up to 14,000 tasks per day, with minimal increase in costs, after migrating from another vendor-managed Apache Airflow solution to AWS, using Amazon Managed Workflows for Apache Airflow (Amazon MWAA) and Amazon Elastic Container Service (Amazon ECS). We walk you through the issues we ran into during the migration, the technical solution we implemented, the trade-offs we made, and lessons we learned along the way.

The challenge

LaunchDarkly has a mission to enable high-velocity teams to release, monitor, and optimize software in production. The centralized data team is responsible for tracking how LaunchDarkly is progressing toward that mission. Additionally, this team is responsible for the majority of the company’s internal data needs, which include ingesting, warehousing, and reporting on the company’s data. Some of the large datasets we manage include product usage, customer engagement, revenue, and marketing data.

As the company grew, our data volume increased, and the complexity and use cases of our workloads expanded exponentially. While using other vendor-managed Airflow-based solutions, our data analytics team faced new challenges on time to integrate and onboard new AWS services, data locality, and a non-centralized orchestration and monitoring solution across different engineering teams within the organization.

Solution overview

LaunchDarkly has a long history of using AWS services to solve business use cases, such as scaling our ingestion from 1 TB to 100 TB per day with Amazon Kinesis Data Streams. Similarly, migrating to Amazon MWAA helped us scale and optimize our internal extract, transform, and load (ETL) pipelines. We used existing monitoring and infrastructure as code (IaC) implementations and eventually extended Amazon MWAA to other teams, establishing it as a centralized batch processing solution orchestrating multiple AWS services.

The solution for our transformation jobs include the following components:

Our original plan for the Amazon MWAA migration was:

  1. Create a new Amazon MWAA instance using Terraform following LaunchDarkly service standards.
  2. Lift and shift (or rehost) our code base from Airflow 1.12 to Airflow 2.5.1 on the original cloud provider to the same version on Amazon MWAA.
  3. Cut over all Directed Acyclic Graph (DAG) runs to AWS.
  4. Upgrade to Airflow 2.
  5. With the flexibility and ease of integration within AWS ecosystem, iteratively make enhancements around containerization, logging, and continuous deployment.

Steps 1 and 2 were executed quickly—we used the Terraform AWS provider and the existing LaunchDarkly Terraform infrastructure to build a reusable Amazon MWAA module initially at Airflow version 1.12. We had an Amazon MWAA instance and the supporting pieces (CloudWatch and artifacts S3 bucket) running on AWS within a week.

When we started cutting over DAGs to Amazon MWAA in Step 3, we ran into some issues. At the time of migration, our Airflow code base was centered around a custom operator implementation that created a Python virtual environment for our workload requirements on the Airflow worker disk assigned to the task. By trial and error in our migration attempt, we learned that this custom operator was essentially dependent on the behavior and isolation of Airflow’s Kubernetes executors used in the original cloud provider platform. When we began to run our DAGs concurrently on Amazon MWAA (which uses Celery Executor workers that behave differently), we ran into a few transient issues where the behavior of that custom operator could affect other running DAGs.

At this time, we took a step back and evaluated solutions for promoting isolation between our running tasks, eventually landing on Fargate for ECS tasks that could be started from Amazon MWAA. We had initially planned to move our tasks to their own isolated system rather than having them run directly in Airflow’s Python runtime environment. Due to the circumstances, we decided to advance this requirement, transforming our rehosting project into a refactoring migration.

We chose Amazon ECS on Fargate for its ease of use, existing Airflow integrations (ECSRunTaskOperator), low cost, and lower management overhead compared to a Kubernetes-based solution such as Amazon Elastic Kubernetes Service (Amazon EKS). Although a solution using Amazon EKS would improve the task provisioning time even further, the Amazon ECS solution met the latency requirements of the data analytics team’s batch pipelines. This was acceptable because these queries run for several minutes on a periodic basis, so a couple more minutes for spinning up each ECS task didn’t significantly impact overall performance.

Our first Amazon ECS implementation involved a single container that downloads our project from an artifacts repository on Amazon S3, and runs the command passed to the ECS task. We trigger those tasks using the ECSRunTaskOperator in a DAG in Amazon MWAA, and created a wrapper around the built-in Amazon ECS operator, so analysts and engineers on the data analytics team could create new DAGs just by specifying the commands they were already familiar with.

The following diagram illustrates the DAG and task deployment flows.

End-to-end AWS workflow diagram illustrating automated DAGs and Tasks deployment through GitHub, CircleCI, S3, MWAA, and ECS

When our initial Amazon ECS implementation was complete, we were able to cut all of our existing DAGs over to Amazon MWAA without the prior concurrency issues, because each task ran in its own isolated Amazon ECS task on Fargate.

Within a few months, we proceeded to Step 4 to upgrade our Amazon MWAA instance to Airflow 2. This was a major version upgrade (from 1.12 to 2.5.1), which we implemented by following the Amazon MWAA Migration Guide and subsequently tearing down our legacy resources.

The cost increase of adding Amazon ECS to our pipelines was minimal. This was because our pipelines run on batch schedules, and therefore aren’t active at all times, and Amazon ECS on Fargate only charges for vCPU and memory resources requested to complete the tasks.

As a part of Step 5 for continuous assessment and improvements, we enhanced our Amazon ECS implementation to push logs and metrics to Datadog and CloudWatch. We could monitor for errors and model performance, and catch data test failures alongside existing LaunchDarkly monitoring.

Scaling the solution beyond internal analytics

During the initial implementation for the data analytics team, we created an Amazon MWAA Terraform module, which enabled us to quickly spin up more Amazon MWAA environments and share our work with other engineering teams. This allowed the use of Airflow and Amazon MWAA to power batch pipelines within the LaunchDarkly product itself in a couple of months shortly after the data analytics team completed the initial migration.

The numerous AWS service integrations supported by Airflow, the built-in Amazon provider package, and Amazon MWAA allowed us to expand our usage across teams to use Amazon MWAA as a generic orchestrator for distributed pipelines across services like Amazon Athena, Amazon Relational Database Service (Amazon RDS), and AWS Glue. Since adopting the service, onboarding a new AWS service to Amazon MWAA has been straightforward, typically involving the identification of the existing Airflow Operator or Hook to use, and then connecting the two services with AWS Identity and Access Management (IAM).

Lessons and results

Through our journey of orchestrating data pipelines at scale with Amazon MWAA and Amazon ECS, we’ve gained valuable insights and lessons that have shaped the success of our implementation. One of the key lessons learned was the importance of isolation. During the initial migration to Amazon MWAA, we encountered issues with our custom Airflow operator that relied on the specific behavior of the Kubernetes executors used in the original cloud provider platform. This highlighted the need for isolated task execution to maintain the reliability and scalability of our pipelines.

As we scaled our implementation, we also recognized the importance of monitoring and observability. We enhanced our monitoring and observability by integrating with tools like Datadog and CloudWatch, so we could better monitor errors and model performance and catch data test failures, improving the overall reliability and transparency of our data pipelines.

With the previous Airflow implementation, we were running approximately 100 Airflow tasks per day across one team and two services (Amazon ECS and Snowflake). As of the time of writing this post, we’ve scaled our implementation to three teams, four services, and execution of over 14,000 Airflow tasks per day. Amazon MWAA has become a critical component of our batch processing pipelines, increasing the speed of onboarding new teams, services, and pipelines to our data platform from weeks to days.

Looking ahead, we plan to continue iterating on this solution to expand our use of Amazon MWAA to additional AWS services such as AWS Lambda and Amazon Simple Queue Service (Amazon SQS), and further automate our data workflows to support even greater scalability as our company grows.

Conclusion

Effective data orchestration is essential for organizations to gather and unify data from diverse sources into a centralized, usable format for analysis. By automating this process across teams and services, businesses can transform fragmented data into valuable insights to drive better decision-making. LaunchDarkly has achieved this by using managed services like Amazon MWAA and adopting best practices such as task isolation and observability, enabling the company to accelerate innovation, mitigate risks, and shorten the time-to-value of its product offerings.

If your organization is planning to modernize its data pipelines orchestration, start assessing your current workflow management setup, exploring the capabilities of Amazon MWAA, and considering how containerization could benefit your workflows. With the right tools and approach, you can transform your data operations, drive innovation, and stay ahead of growing data processing demands.


About the Authors

Asena Uyar is a Software Engineer at LaunchDarkly, focusing on building impactful experimentation products that empower teams to make better decisions. With a background in mathematics, industrial engineering, and data science, Asena has been working in the tech industry for over a decade. Her experience spans various sectors, including SaaS and logistics, and she has spent a significant portion of her career as a Data Platform Engineer, designing and managing large-scale data systems. Asena is passionate about using technology to simplify and optimize workflows, making a real difference in the way teams operate.

Dean Verhey is a Data Platform Engineer at LaunchDarkly based in Seattle. He’s worked all across data at LaunchDarkly, ranging from internal batch reporting stacks to streaming pipelines powering product features like experimentation and flag usage charts. Prior to LaunchDarkly, he worked in data engineering for a variety of companies, including procurement SaaS, travel startups, and fire/EMS records management. When he’s not working, you can often find him in the mountains skiing.

Daniel Lopes is a Solutions Architect for ISVs at AWS. His focus is on enabling ISVs to design and build their products in alignment with their business goals with all advantages AWS services can provide them. His areas of interest are event-driven architectures, serverless computing, and generative AI. Outside work, Daniel mentors his kids in video games and pop culture.

How Flutter UKI optimizes data pipelines with AWS Managed Workflows for Apache Airflow

Post Syndicated from Monica Cujerean, Ionut Hedesiu original https://aws.amazon.com/blogs/big-data/how-flutter-uki-optimizes-data-pipelines-with-aws-managed-workflows-for-apache-airflow/

This post is co-written with Monica Cujerean and Ionut Hedesiu from Flutter UKI.

In this post, we share how Flutter UKI transitioned from a monolithic Amazon Elastic Compute Cloud (Amazon EC2)-based Airflow setup to a scalable and optimized Amazon Managed Workflows for Apache Airflow (Amazon MWAA) architecture using features like Kubernetes Pod Operator, continuous integration and delivery (CI/CD) integration, and performance optimization techniques.

About Flutter UKI

As a division of Flutter Entertainment, Flutter UKI stands at the forefront of the sports betting and gaming industry. Flutter UKI offers a diverse portfolio of entertainment options, encompassing sports wagering, casino games, bingo, and poker experiences. Flutter UKI’s digital presence is robust, operating through an array of renowned online brands. These include the iconic Paddy Power, Sky Betting and Gaming, and Tombola. While Flutter UKI has established a strong online foothold, it maintains a significant physical presence with a network of 576 Paddy Power betting shops strategically located across the United Kingdom and Ireland.

The Data team at Flutter UKI is integral to the company’s mission of using data to drive business success and innovation. Specializing in data, their teams are dedicated to ensuring the seamless integration, management, and accessibility of data across multiple facets of the organization. By developing robust data pipelines and maintaining high data quality standards, Flutter UKI empowers stakeholders with reliable insights, optimizes operational efficiencies, and enhances the user experience. Its commitment to data excellence underpins its efforts to remain at the forefront of the online gaming and entertainment industry, delivering value and strategic advantage to the business.

The journey from self managing Airflow on Amazon EC2 to operating Airflow workloads at scale using Amazon MWAA

Flutter UKI’s data orchestration story began in 2017 with a modest Apache Airflow deployment on EC2 instances. As the company’s digital footprint expanded, so did their data pipeline requirements, leading to an increasingly complex monolithic cluster that demanded constant attention and resource scaling. The operational overhead of managing these EC2 instances became a significant challenge for their engineering teams. In 2022, Flutter UKI reached a crossroads. They needed to choose between re-architecting their service on Amazon Elastic Kubernetes Service (Amazon EKS) or embracing Amazon Managed Workflows for Apache Airflow (MWAA).

Flutter UKI was looking to transform their data orchestration service from a resource-intensive, self-managed system to a more efficient, managed service that would allow them to focus on their core business objectives rather than infrastructure management. Through extensive proof-of-concept (POC) testing and close collaboration with AWS Enterprise Support, Flutter UKI gained confidence in the ability of Amazon MWAA to handle their sophisticated workloads at scale. Their choice of MWAA over a self-managed solution on Amazon EKS reflected Flutter UKI’s strategic focus on using managed services to reduce operational complexity and accelerate innovation.

The migration to Amazon MWAA followed a methodical approach. There was extensive testing of multiple POCs. During the POCs, the engineering team found MWAA to have a good ease of use, which helped them reduce the learning curve resulting in faster. Learning from each POC, they iterated on the final architecture by making data-driven decisions. Starting with a small subset of directed acyclic graphs (DAG), the Flutter UKI team expanded their deployment over time, gradually moving hundreds and eventually thousands of workflows to the managed service. This careful, phased transition allowed them to validate the performance and reliability of MWAA while minimizing operational risk.

High-level architecture design

During the service re-architecture, the data team strategically managed over 3,500 dynamically generated DAGs by implementing a sophisticated distribution approach across multiple Amazon MWAA environments to create a workload isolated environment. Another reason for having multiple environments was to make sure that no one MWAA environment doesn’t get overloaded by multiple DAGs. By placing DAG files across diverse Amazon Simple Storage Service (Amazon S3) locations and configuring unique DAG_FOLDER paths for each environment, the data team created an intelligent load balancing mechanism that allocates workflows based on complex criteria including environment type, task volume, and environment-specific DAG affinity. A round-robin distribution strategy was designed to minimize single environment load, ensuring scalable infrastructure with zero performance degradation. This approach allowed the team to optimize workflow orchestration, maintaining high performance while efficiently managing an extensive collection of dynamically generated DAGs across multiple MWAA environments. To provide more compute to individual tasks and to keep the MWAA efficient, Flutter UKI delegated the DAG execution to an external compute environment using Amazon Elastic Kubernetes Service (Amazon EKS). The resulting high-level architecture is shown in the following figure.

  1. Kubernetes Pod Operator (KPO) for tasks: Flutter UKI transitioned from using custom operators and many native Airflow operators to exclusively utilizing the Kubernetes Pod Operator (KPO). This decision simplified their architecture by eliminating unnecessary complexity, reducing maintenance overhead, and mitigating potential bugs. Additionally, this approach enabled them to allocate compute resources on a per-task basis, optimizing overall service performance. It also enabled the use of different container images for different tasks, thereby avoiding library dependency conflicts.
  2. Kubernetes Pod Operator wrapper (KPOw): Instead of using KPO directly, they developed a wrapper (KPOw) around it. This wrapper abstracts the underlying complexity and minimizes the impact of signature changes in Airflow, Amazon MWAA, Amazon EKS, or operator versions. By centralizing these changes, they only need to update the wrapper rather than thousands of individual DAGs. The wrapper also simplifies DAGs by hiding repetitive parameters, such as node affinity, pod resources, and EKS cluster configurations. Furthermore, it enforces company-specific naming conventions and allows for parameter validation at task execution time rather than during DagBag refresh. They also introduced profiles and image files, where profile files contain necessary KPO parameters, and the corresponding image files link to the repository for the task’s container image. This setup ensures consistency across tasks using the same profile and facilitates simultaneous updates across tasks.
  3. Monthly image updates in Kubernetes: Enforcing a policy of monthly image updates made sure that their code remained current, preventing security vulnerabilities and avoiding extensive code changes due to deprecated libraries.
  4. Continuous Airflow updates: Flutter UKI maintains a cutting-edge infrastructure by implementing new Airflow versions shortly after release, while following a carefully orchestrated deployment strategy. Their approach uses standard Amazon MWAA configurations and employs a systematic testing protocol. New versions are first deployed to development and test environments for thorough validation before reaching production systems. This methodical progression significantly reduces the risk of disruptions to business-critical workflows.

To achieve operational excellence, Flutter UKI has implemented a comprehensive monitoring framework centered on Amazon CloudWatch metrics. Their monitoring solution includes strategically configured alarms that provide early warning signals for potential issues. This proactive monitoring approach enables their teams to quickly identify and investigate anomalies in production workload executions, ensuring high availability and performance of their data pipelines. The combination of careful version management and robust monitoring exemplifies Flutter UKI’s commitment to operational excellence in their cloud infrastructure.

  1. CI/CD integration: By managing their code in GitLab, with mandatory code reviews and using Argo Events and Argo Workflows for image updates in AWS ECR, they streamlined their development processes.
  2. Performance Optimization: A significant portion of the DAGs are dynamically generated based on database metadata. This generation process runs outside Amazon MWAA, with its own CI/CD pipeline, and the resulting DAG files are stored in the S3 DAG. Placing code outside of tasks was avoided, including parameter evaluation. Parameters and secrets are stored in AWS Secrets Manager and retrieved at task runtime. Engineers aim to minimize or eliminate inter-service dependencies within MWAA.

DAGs are scheduled to distribute execution times as evenly as possible. Task code and common modules are hosted on Amazon S3 and retrieved at runtime. For larger codebases, Amazon Elastic File System (Amazon EFS) volumes are mounted to task pods are used.

Results

Today, Flutter UKI’s infrastructure comprises four Amazon MWAA clusters, each executing tasks on dedicated Amazon EKS node groups. They manage approximately 5,500 DAGs encompassing over 30,000 tasks, handling more than 60,000 DAG runs daily with a concurrency exceeding 450 tasks running simultaneously across clusters. They anticipate a 10% monthly increase in this workload in the short to medium term. During major events like Cheltenham and Grand National, where data load increases by 30%, their MWAA service has demonstrated stability and scalability, achieving a 100% success rate for critical processes in 2025, a significant improvement over previous years.

Conclusion

Flutter UKI’s journey with AWS Managed Workflows for Apache Airflow (Amazon MWAA) has resulted in a stable, scalable, and resilient production environment. The careful re-architecting of Flutter UKI’s service, combined with strategic decisions around task execution and infrastructure management, has not only simplified their operations, but also enhanced performance and reliability. Security and compliance benefits were also noticed, because MWAA provides managed security updates, built-in encryption, and integration with AWS security services. Perhaps most importantly, the shift to MWAA has allowed Flutter UKI’s engineering teams to redirect their efforts from infrastructure maintenance to business-critical tasks, focusing on DAG development and improving data pipeline efficiency, ultimately accelerating innovation in their core business operations.

If you’re looking to reduce operational overhead and migrate to a fully managed Airflow solution on AWS, consider using Amazon MWAA. Get in touch with your Technical Account Manager or your Solutions Architect to discuss a solution specific to your use-case. You can also reach out to AWS Support by creating a case if you’re facing an issues setting up the service.

Ready to see what Amazon MWAA is like? Visit the AWS Management Console for Amazon MWAA. For more information, see What Is Amazon Managed Workflows for Apache Airflow. Additionally, Using Amazon MWAA with Amazon EKS shows you how to integrate Amazon MWAA with Amazon EKS.


About the authors

Monica Cujerean is a Principal Data Engineer at Flutter UKI, focusing on service related initiatives that cover performance optimization, cost effectiveness, and new feature adoption on most AWS service in our stack: Amazon MWAA, Amazon Redshift, Amazon Aurora, and Amazon SageMaker.

Ionut Hedesiu is a Senior Data Architect at Flutter UKI, responsible for designing strategic solutions to cover complex and varied business needs. His main expertise is on Amazon MWAA, Kubernetes, Amazon Sagemaker, and ETL solutions.

Nidhi Agrawal is a Technical Account Manager at AWS and works with large enterprise customers to provide the technical guidance, best practices, and strategic support to customers, helping them optimize their environments in the AWS Cloud.

John Kellett is a Senior Customer Solutions Manager with 25 years of experience across private and public sectors. John helps drive end-to-end customer engagement through program management excellence. By understanding and representing customers’ strategic visions, John aligns to develop the people, organizational readiness, and technology competencies to meet the desired outcomes.

Sidhanth Muralidhar is a Principal Technical Account Manager at AWS. He works with large enterprise customers who run their workloads on AWS. He is passionate about working with customers and helping them architect workloads for cost, reliability, performance, and operational excellence at scale in their cloud journey. He has a keen interest in data analytics as well.

How BMW Group built a serverless terabyte-scale data transformation architecture with dbt and Amazon Athena

Post Syndicated from Philipp Karg original https://aws.amazon.com/blogs/big-data/how-bmw-group-built-a-serverless-terabyte-scale-data-transformation-architecture-with-dbt-and-amazon-athena/

Businesses increasingly require scalable, cost-efficient architectures to process and transform massive datasets. At the BMW Group, our Cloud Efficiency Analytics (CLEA) team has developed a FinOps solution to optimize costs across over 10,000 cloud accounts. While enabling organization-wide efficiency, the team also applied these principles to the data architecture, making sure that CLEA itself operates frugally. After evaluating various tools, we built a serverless data transformation pipeline using Amazon Athena and dbt.

This post explores our journey, from the initial challenges to our current architecture, and details the steps we took to achieve a highly efficient, serverless data transformation setup.

Challenges: Starting from a rigid and costly setup

In our early stages, we encountered several inefficiencies that made scaling difficult. We were managing complex schemas with wide tables that required significant effort in maintainability. Initially, we used Terraform to create tables and views in Athena, allowing us to manage our data infrastructure as code (IaC) and automate deployments through continuous integration and delivery (CI/CD) pipelines. However, this method slowed us down when changing data models or dealing with schema changes, therefore requiring high development efforts.

As our solution grew, we faced challenges with query performance and costs. Each query scanned large amounts of raw data, resulting in increased processing time and higher Athena costs. We used views to provide a clean abstraction layer, but this masked underlying complexity because seemingly simple queries against these views scanned large volumes of raw data, and our partitioning strategy wasn’t optimized for these access patterns. As our datasets grew, the lack of modularity in our data design increased complexity, making scalability and maintenance increasingly difficult. We needed a solution for pre-aggregating, computing, and storing query results of computationally intensive transformations. The absence of robust testing and lineage solutions made it challenging to identify the root causes of data inconsistencies when they occurred.

As part of our business intelligence (BI) solution, we used Amazon QuickSight to build our dashboards, providing visual insights into our cloud cost data. However, our initial data architecture led to challenges. We were building dashboards on top of large, wide datasets, with some hitting the QuickSight per-dataset SPICE limit of 1 TB. Additionally, during SPICE ingest, our largest datasets required 4–5 hours of processing time due to performing full scans each time, often scanning over a terabyte of data. This architecture wasn’t helping us be more agile and quick while scaling up. The long processing times and storage limitations hindered our ability to provide timely insights and expand our analytics capabilities.

To address these issues, we enhanced the data architecture with AWS Lambda, AWS Step Functions, AWS Glue, and dbt. This tool stack significantly enhanced our development agility, empowering us to quickly modify and introduce new data models. At the same time, we improved our overall data processing efficiency with incremental loads and better schema management.

Solution overview

Our current architecture consists of a serverless and modular pipeline coordinated by GitHub Actions workflows. We chose Athena as our primary query engine for several strategic reasons: it aligns perfectly with our team’s SQL expertise, excels at querying Parquet data directly in our data lake, and alleviates the need for dedicated compute resources. This makes Athena an ideal fit for CLEA’s architecture, where we process around 300 GB daily from a data lake of 15 TB, with our largest dataset containing 50 billion rows across up to 400 columns. The capability of Athena to efficiently query large-scale Parquet data, combined with its serverless nature, enables us to focus on writing efficient transformations rather than managing infrastructure.

The following diagram illustrates the solution architecture.

Using this architecture, we’ve streamlined our data transformation process using dbt. In dbt, a data model represents a single SQL transformation that creates either a table or a view—essentially a building block of our data transformation pipeline. Our implementation includes around 400 such models, 50 data sources, and around 100 data tests. This setup enables seamless updates—whether creating new models, updating schemas, or modifying views—triggered simply by creating a pull request in our source code repository, with the rest handled automatically.

Our workflow automation includes the following features:

  • Pull request – When we create a pull request, it’s deployed to our testing environment first. After passing validation and being approved or merged, it’s deployed to production using GitHub workflows. This setup enables seamless model creation, schema updates, or view changes—triggered just by creating a pull request, with the rest handled automatically.
  • Cron scheduler – For nightly runs or multiple daily runs to reduce data latency, we use scheduled GitHub workflows. This setup allows us to configure specific models with different update strategies based on data needs. We can set models to update incrementally (processing only new or changed data), as views (querying without materializing data), or as full loads (completely refreshing the data). This flexibility optimizes processing time and resource usage. We can target only specific folders—like source, prepared, or semantic layers—and run the dbt test afterward to validate model quality.
  • On demand – When adding new columns or changing business logic, we need to update historical data to maintain consistency. For this, we use a backfill process, which is a custom GitHub workflow created by our team. The workflow allows us to select specific models, include their upstream dependencies, and set parameters like start and end dates. This makes sure that changes are applied accurately across the entire historical dataset, maintaining data consistency and integrity.

Our pipeline is organized into three primary stages—Source, Prepared, and Semantic—each serving a specific purpose in our data transformation journey. The Source stage maintains raw data in its original form. The Prepared stage cleanses and standardizes this data, handling tasks like deduplication and data type conversions. The Semantic stage transforms this prepared data into business-ready models aligned with our analytical needs. An additional QuickSight step handles visualization requirements. To achieve low cost and high performance, we use dbt models and SQL code to manage all transformations and schema changes. By implementing incremental processing strategies, our models process only new or changed data rather than reprocessing the entire dataset with each run.

The Semantic stage (not to be confused with dbt’s semantic layer feature) introduces business logic, transforming data into aggregated datasets that are directly consumable by BMW’s Cloud Data Hub, internal CLEA dashboards, data APIs, or In-Console Cloud Assistant (ICCA) chatbot. The QuickSight step further optimizes data by selecting only necessary columns by using a column-level lineage solution and setting a dynamic date filter with a sliding window to ingest only relevant hot data into SPICE, avoiding unused data in dashboards or reports.

This approach aligns with BMW Group’s broader data strategy, which includes streamlining data access using AWS Lake Formation for fine-grained access control.

Overall, as a high-level structure, we’ve fully automated schema changes, data updates, and testing through GitHub pull requests and dbt commands. This approach enables controlled deployment with robust version control and change management. Continuous testing and monitoring workflows uphold data accuracy, reliability, and quality across transformations, supporting efficient, collaborative model iteration.

Key benefits of the dbt-Athena architecture

To design and manage dbt models effectively, we use a multi-layered approach combined with cost and performance optimizations. In this section, we discuss how our approach has yielded significant benefits in five key areas.

SQL-based, developer-friendly environment

Our team already had strong SQL skills, so dbt’s SQL-centric approach was a natural fit. Instead of learning a new language or framework, developers could immediately start writing transformations using familiar SQL syntax with dbt. This familiarity aligns well with the SQL interface of Athena and, combined with dbt’s added functionality, has increased our team’s productivity.

Behind the scenes, dbt automatically handles synchronization between Amazon Simple Storage Service (Amazon S3), the AWS Glue Data Catalog, and our models. When we need to change a model’s materialization type—for example, from a view to a table—it’s as simple as updating a configuration parameter rather than rewriting code. This flexibility has reduced our development time dramatically, allowed us to focus on building better data models rather than managing infrastructure.

Agility in modeling and deployment

Documentation is crucial for any data platform’s success. We use dbt’s built-in documentation capabilities by publishing them to GitHub Pages, which creates an accessible, searchable repository of our data models. This documentation includes table schemas, relationships between models, and usage examples, enabling team members to understand how models interconnect and how to use them effectively.

We use dbt’s built-in testing capabilities to implement comprehensive data quality checks. These include schema tests that verify column uniqueness, referential integrity, and null constraints, as well as custom SQL tests that validate business logic and data consistency. The testing framework runs automatically on every pull request, validating data transformations at each step of our pipeline. Additionally, dbt’s dependency graph provides a visual representation of how our models interconnect, helping us understand the upstream and downstream impacts of any changes before we implement them. When stakeholders need to modify models, they can submit changes through pull requests, which, after they’re approved and merged, automatically trigger the necessary data transformations through our CI/CD pipeline. This streamlined process enabled us to create new data products within days compared to weeks and reduced ongoing maintenance work by catching issues early in the development cycle.

Athena workgroup separation

We use Athena workgroups to isolate different query patterns based on their execution triggers and purposes. Each workgroup has its own configuration and metric reporting, allowing us to monitor and optimize separately. The dbt workgroup handles our scheduled nightly transformations and on-demand updates triggered by pull requests through our Source, Prepared, and Semantic stages. The dbt-test workgroup executes automated data quality checks during pull request validation and nightly builds. The QuickSight workgroup manages SPICE data ingestion queries, and the Ad-hoc workgroup supports interactive data exploration by our team.

Each workgroup can be configured with specific data usage quotas, enabling teams to implement granular governance policies. This separation provides several benefits: it enables clear cost allocation, provides isolated monitoring of query patterns across different use cases, and helps enforce data governance through custom workgroup settings. Amazon CloudWatch monitoring per workgroup helps us track usage patterns, identify query performance issues, and adjust configurations based on actual needs.

Using QuickSight SPICE

QuickSight SPICE (Super-fast, Parallel, In-memory Calculation Engine) provides powerful in-memory processing capabilities that we’ve optimized for our specific use cases. Rather than loading entire tables into SPICE, we create specialized views on top of our materialized semantic models. These views are carefully crafted to include only the necessary columns, relevant metadata joins, and appropriate time filtering to have only recent data available in dashboards.

We’ve implemented a hybrid refresh strategy for these SPICE datasets: daily incremental updates keep the data fresh, and weekly full refreshes maintain data consistency. This approach strikes a balance between data freshness and processing efficiency. The result is responsive dashboards that maintain high performance while keeping processing costs under control.

Scalability and cost-efficiency

The serverless architecture of Athena eliminates manual infrastructure management, automatically scaling based on query demand. Because costs are based solely on the amount of data scanned by queries, optimizing queries to scan as little data as possible directly reduces our costs. We use the distributed query execution capabilities of Athena through our dbt model structure, enabling parallel processing across data partitions. By implementing effective partitioning strategies and using Parquet file format, we minimize the amount of data scanned while maximizing query performance.

Our architecture offers flexibility in how we materialize data through views, full tables, and incremental tables. With dbt’s incremental models and partitioning strategy, we process only new or modified data instead of entire datasets. This approach has proven highly effective—we’ve observed significant reductions in data processing volume as well as data scanning, particularly in our QuickSight workgroup.

The effectiveness of these optimizations implemented at the end of 2023 is visible in the following diagram, showing costs by Athena workgroups.

The workgroups are illustrated as follows:

  • Green (QuickSight): Shows reduced data scanning post-optimization.
  • Light blue (Ad-hoc): Varies based on analysis needs.
  • Dark blue (dbt): Maintains consistent processing patterns
  • Orange (dbt-test): Shows regular, efficient test execution.

The increased dbt workload costs directly correlate with decreased QuickSight costs, reflecting our architectural shift from using complex views in QuickSight workgroups (which previously masked query complexity but led to repeated computations) to using dbt for materializing these transformations. Although this increased the dbt workload, the overall cost-efficiency improved significantly because materialized tables reduced redundant computations in QuickSight. This demonstrates how our optimization strategies successfully manage growing data volumes while achieving net cost reduction through efficient data materialization patterns.

Conclusion

Our data architecture uses dbt and Athena to provide a scalable, cost-efficient, and flexible framework for building and managing data transformation pipelines. Athena’s ability to query data directly in Amazon S3 alleviates the need to move or copy data into a separate data warehouse, and its serverless model and dbt’s incremental processing minimize both operational overhead and processing costs. Given our team’s strong SQL expertise, expressing these transformations in SQL through dbt and Athena was a natural choice, enabling rapid model development and deployment. With dbt’s automatic documentation and lineage, troubleshooting and identifying data issues is simplified, and the system’s modularity allows for quick adjustments to meet evolving business needs.

Starting with this architecture is quick and straightforward: all that is needed is the dbt-core and dbt-athena libraries, and Athena itself requires no setup, because it’s a fully serverless service with seamless integration with Amazon S3. This architecture is ideal for teams looking to rapidly prototype, test, and deploy data models, optimizing resource usage, accelerating deployment, and providing high-quality, accurate data processing.

For those interested in a managed solution from dbt, see From data lakes to insights: dbt adapter for Amazon Athena now supported in dbt Cloud.


About the Authors

Philipp Karg is a Lead FinOps Engineer at BMW Group and has a strong background in data engineering, AI, and FinOps. He focuses on driving cloud efficiency initiatives and fostering a cost-aware culture within the company to leverage the cloud sustainably.

Selman Ay is a Data Architect specializing in end-to-end data solutions, architecture, and AI on AWS. Outside of work, he enjoys playing tennis and engaging outdoor activities.

Cizer Pereira is a Senior DevOps Architect at AWS Professional Services. He works closely with AWS customers to accelerate their journey to the cloud. He has a deep passion for cloud-based and DevOps solutions, and in his free time, he also enjoys contributing to open source projects.