Tag Archives: Events

Your Cloud Detection Strategy in 2026: What to Expect at the Global Cybersecurity Summit

Post Syndicated from Emma Burdett original https://www.rapid7.com/blog/post/it-2026-cloud-detection-strategy-global-cybersecurity-summit

Cloud environments have changed how security teams detect and respond to threats. Signals come from more places, identities are harder to track, and attacks rarely stay within a single system. For many teams, the challenge is no longer visibility. It is having the risk context to understand what matters and act on it quickly. This shift is reflected in the conversations shaping this year’s Rapid7 Global Cybersecurity Summit.

Taking place May 12-13, the summit explores how detection and response are evolving across cloud, identity, and endpoint environments. The focus is practical: how attacks actually unfold, how teams respond under pressure, and how detection strategies need to adapt.

Detection is no longer just about coverage

One of the clearest themes across the agenda is that traditional detection models are struggling to keep pace with attackers. Environments are more dynamic, and attackers are more targeted. Catching everything is no longer realistic, and in many cases it is not useful.

Sessions like The New Rules of Detection Engineering will examine this shift in detail. The focus moves away from volume and toward precision. It will ask questions like: What makes a detection meaningful? How should teams prioritize signals? And how can detection strategies support real outcomes rather than just generate alerts? This is especially important in cloud environments, where context changes quickly and signals are often incomplete.

Understanding how attacks actually unfold

To improve detection, teams need to understand how attacks behave in practice. Several sessions across the summit focus on this directly.

The Reality of Running a SOC in 2026 will explore how modern attacks begin — from identity misuse to cloud misconfigurations— and how they evolve over time. Rather than following a predictable path, attacks move across systems, taking advantage of gaps in visibility and delayed decisions.

This theme continues in sessions like Inside the Modern SOC, where attendees follow a real investigation from first alert to outcome. These walkthroughs show how signals are correlated across environments and how decisions are made when time and clarity are limited.

From exposure to runtime risk

Cloud security also requires a closer connection between exposure and detection. In many cases, incidents begin long before an alert is triggered.

Sessions such as From Cloud Exposure to Runtime Attack explore how misconfigurations, permissions, and overlooked risks lead to active threats. The focus is on how teams connect exposure insights with runtime behavior to improve prioritization and respond earlier in the attack lifecycle.

This is a practical shift. Detection is no longer a separate function but part of a broader process that starts with understanding exposure and continues through to response.

What this means for security teams

Across these sessions, a consistent message emerges: Detection strategies need to be grounded in how environments actually behave, not how they are expected to behave.

This means focusing on signal quality rather than volume, connecting data across cloud, identity, and endpoint, and building workflows that support faster decisions. It also means accepting that not all alerts have equal weight, and that prioritization is a core part of modern detection.

A preview of what’s to come

Cloud detection is just one part of a broader shift happening across the summit. Sessions on MDR, AI, and exposure management all connect back to the same idea. Security operations must move earlier, reduce noise, and act with greater confidence.

If you are rethinking how your team detects and responds to threats in cloud and hybrid environments, this is where those conversations come together.

Join us May 12–13 and see how security teams are evolving their detection strategies for 2026.

Register now.

A First Look at Our Speaker Lineup and Agenda for the Rapid7 2026 Global Cybersecurity Summit

Post Syndicated from Emma Burdett original https://www.rapid7.com/blog/post/it-speaker-lineup-first-look-agenda-rapid7-2026-global-cybersecurity-summit

The agenda for the Rapid7 2026 Global Cybersecurity Summit is starting to take shape, and with it, a clearer picture of the conversations security teams need to be having right now.

Taking place May 12–13, this year’s summit brings together a mix of security leaders, practitioners, analysts, and industry voices to explore how organizations are moving from reactive defense to preemptive security operations. The focus is practical. What is changing, what is not working, and what teams need to do differently.

Voices from across the industry

This year’s lineup reflects that shift. Alongside Rapid7 experts and customer speakers, the summit will feature well-known voices from across the security community.

Rachel Tobac, CEO of SocialProof Security, joins the keynote panel The Reality of Running a SOC in 2026, bringing a perspective grounded in how modern attacks actually begin and how attackers adapt in real time. She is joined by cybersecurity speaker and “Smashing Security” podcast host Graham Cluley, whose work has long focused on translating complex threats into practical understanding for security teams.

From an analyst perspective, Craig Robinson of IDC and Dave Gruber of Omdia add an external view on how the market is evolving, where organizations are investing, and how security programs are being measured. Their contributions help ground the discussion in broader industry trends, not just individual experiences.

Customer voices also play a central role. Leaders from organizations such as Netscout Systems, Target RWE, and Miltenyi Biotecwill share how they are navigating complexity, validating decisions around MDR and platform consolidation, and focusing on outcomes rather than activity.

What to expect during the show

Across two days, the summit is structured to reflect how security teams actually operate.

Day one focuses on shared context with sessions like Defense Starts Earlier Than You Think and The Reality of Running a SOC in 2026 examining how the threat landscape has shifted and why traditional approaches are struggling to keep pace. From there, sessions such as Inside the Modern SOC and Using Red Teaming to Power Preemptive MDR move into how detection, response, and validation work in practice.

The goal is to connect the full picture: how attacks begin, how they progress, and how teams respond when it matters.

Day two is more focused on the unique needs of particular security roles. The two dedicated tracks allow attendees to go deeper into the implications of modern security evolution based on their daily realities.

For security leaders, sessions such as The CISO’s Role in Enterprise Transformation and A CISO’s Guide to MDR Accountability and Outcomes explore governance, accountability, and ways to measure effectiveness that reflect real business risk.

For practitioners, sessions like Hunt or Be Hunted and IR in Practice focus on the mechanics of investigation, detection and response. These sessions look closely at how analysts triage signals, how decisions are made under pressure, and how response workflows hold up in real environments.

Across both days, the agenda is designed to move beyond theory with each session connecting back to the same core concept. Security teams need to act earlier, reduce uncertainty, and make decisions with greater confidence.

Secure your spot

If you are looking to understand how security operations are evolving, and how teams are putting that into practice, this is where those conversations come together.

Join us May 12–13 and see how organizations are building more resilient, preemptive security operations.

Register now.

Red Teaming in 2026: What to Expect at our 2026 Global Cybersecurity Summit

Post Syndicated from Emma Burdett original https://www.rapid7.com/blog/post/it-red-teaming-2026-global-cybersecurity-summit

Red teaming has always played a role in testing defenses, but in 2026 its role is changing. Security teams are no longer asking whether an attacker can get in. That question has already been answered. The real challenge is whether teams can detect, validate, and respond before an incident escalates.

That shift sits at the center of this year’s Rapid7 Global Cybersecurity Summit, taking place on May 12-13. As part of the Continuous Threat Defense pillar, the summit will explore red teaming not as a standalone exercise, but as a core input into how modern security operations function day to day.

From validation to continuous feedback

In sessions like Using Red Teaming to Power Preemptive MDR, the focus moves away from point-in-time testing and toward becoming part of a continuous feedback loop. Detection logic is tested against real attacker techniques and gaps are exposed before they become incidents. Response workflows are refined in conditions that reflect how attacks actually unfold, rather than how they are expected to behave.

This represents a clear shift from traditional engagements. Instead of producing a static report, red teaming feeds directly into detection engineering and MDR operations. Many teams still rely on assumptions about coverage, but those assumptions often break down under pressure. Continuous validation helps close that gap.

Aligning red teaming with how attacks really happen

Modern attacks rarely follow a clean path. They move across identity, cloud, and endpoint, taking advantage of timing, visibility gaps, and delayed decisions. Red teaming has to reflect that reality.

At the summit, the conversation connects adversary behavior with how detection and response teams operate in practice. This includes how signals are correlated across environments, how escalation decisions are made, and where teams lose time during an investigation. The goal is not to simulate attacks for the sake of it, but to understand how those attacks would be detected, prioritized, and contained in a real environment.

Why red teaming matters now

The move toward preemptive security operations depends on confidence. Teams need to know that what they have built will hold up when it matters. Red teaming supports that by grounding security programs in evidence. It shows what works, highlights what does not, and gives teams an opportunity to improve before a live incident forces change.

This becomes even more important as organizations adopt MDR models, integrate AI into workflows, and operate across increasingly complex environments. Without continuous validation, complexity creates blind spots that are difficult to see until it is too late.

Rapid7’s Cybersecurity Summit: A preview of what’s to come

Red teaming is one part of a broader shift happening across the summit. Sessions across detection, response, AI, and exposure management all point in the same direction: Security operations must move earlier in the attack lifecycle, reduce noise, improve prioritization, and support faster decisions with better context.

More sessions and speakers will be announced in the coming weeks, building out how this shift is being applied in practice. If you are responsible for detection, response, or validation of your security program, this is a conversation worth being part of.

Join us May 12–13 and see how teams are using red teaming to strengthen modern security operations.

Register now.

From Threat Detection to Response: What to Expect from Our MDR Sessions

Post Syndicated from Emma Burdett original https://www.rapid7.com/blog/post/it-threat-detection-response-mdr-sessions-global-cybersecurity-summit

Detection and response are under pressure. Expanding attack surfaces, identity misuse, cloud sprawl, and AI-accelerated threats have changed what “ready” looks like for a SOC. That’s why this year’s Global Cybersecurity Summit places Continuous Threat Defense at the center of the conversation.

The focus is clear: this is what modern MDR looks like when it’s designed to disrupt attackers earlier, not just react to them faster.

2026 MDR sessions: A sneak peek

Throughout the summit, several sessions will explore how detection and response are evolving in practice. In this year’s “Inside the Modern SOC”, we’ll look at how response actually unfolds when pressure is high and decisions matter. It’s a close examination of ownership, escalation, and how teams coordinate across endpoint, identity, and cloud telemetry.

In “Using Red Teaming to Power Preemptive MDR”, the conversation shifts upstream. Rather than treating red teaming as a compliance exercise, this session examines how continuous testing strengthens detection coverage and validates response workflows before a real attacker forces the issue.

For the executive leaders “A CISO’s Guide to MDR Accountability and Outcomes” will examine MDR through a leadership lens, describing how leaders can best evaluate performance, define success, and ensure response strategies hold up under scrutiny. As detection models grow more complex, clarity around accountability can become just as important as technical capability.

For hands-on practitioners, “Hunt or Be Hunted: Frontline Tales of Detection” offers a scenario-driven walkthrough of how SOC analysts triage signals, manage handoffs, and make decisions under real operational pressure. Meanwhile,” IR in Practice: Tools, Tradecraft, and Adversary-Informed Investigation” provides a deeper look at investigative workflows, including practical use cases and adversary-informed response approaches.

What preemptive MDR really means

Together, these sessions represent part of a broader theme: Preemptive Security Operations is not about adding more tools or generating more alerts. It is about reducing uncertainty, aligning exposure with detection, and building workflows that allow teams to act with confidence.

And this is only a preview. Additional sessions, speakers, and perspectives will continue to be announced as the summit approaches.

If you’re responsible for detection strategy, response readiness, or MDR governance, this track is designed to meet you where you operate. Join us May 12–13 and be part of the shift toward more confident, preemptive security operations.

Register now

Save the Date: Rapid7’s 2026 Global Cybersecurity Summit | May 12–13

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/it-2026-global-cybersecurity-summit-may-12-13

Mark your calendars. The Rapid7 2026 Global Cybersecurity Summit returns May 12–13, bringing together security leaders, practitioners, and industry experts for two days of strategic leadership insight and hands-on operational guidance, designed to equip both decision-makers and defenders to build stronger, more resilient security programs.

This year’s theme is Preemptive Security Operations – a shift from reacting to threats to anticipating and neutralizing them before impact.

Security teams are navigating expanding attack surfaces, AI-accelerated threats, relentless alert fatigue, and increasing pressure to do more with less. The 2026 summit is designed to cut through that complexity and focus on what matters most, helping organizations move from reactive defense to confident, proactive operations.

What to expect from Rapid7’s 2026 summit

Whether you’re shaping security strategy at the executive level or defending systems inside the SOC, the summit will deliver actionable insights you can apply immediately.

Day 1 will focus on the big picture. Designed to bring together security leaders, decision-makers, and practitioners around a shared narrative, the first day will explore the paradigm shift shaping modern security operations. Sessions will examine how MDR is evolving beyond monitoring into proactive defense, how exposure management and threat intelligence are converging with it into unified risk strategies, and how AI is changing both attacker capabilities and defender workflows. The emphasis will be on clarity, alignment, and strategic direction, helping organizations rethink how their SOCs operate in an increasingly complex environment.

Day 2 will go deeper. Structured with dedicated tracks for security leaders and frontline practitioners, the second day will provide focused, role-specific content. Leaders will engage with sessions centered on governance, resilience, and executive accountability, while practitioners will dive into real-world detection scenarios, threat hunting methodologies, red teaming insights, and operational playbooks. This two-track approach reflects the reality facing modern security teams: strategy and execution must move forward together.

Why attend Rapid7’s global cybersecurity summit?

The Rapid7 Virtual Cybersecurity Summit is built for today’s reality where speed, clarity, and confidence matter more than ever. This year’s focus on Preemptive Security Operations reflects a shift from reacting to incidents toward anticipating and reducing risk before impact. Preemptive security means unifying visibility across the attack surface, aligning exposure with detection and response, and using AI and intelligence to prioritize what truly matters. It’s about giving security teams the insight and authority to act earlier, reduce uncertainty, and strengthen resilience across the organization.

If 2025 was about reacting faster, 2026 is about acting sooner, so save the date now and be part of the conversation shaping the future of preemptive security operations.

May 12–13, 2026
Rapid7 Virtual Cybersecurity Summit

Register here

AWS Weekly Roundup: AWS re:Invent keynote recap, on-demand videos, and more (December 8, 2025)

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-reinvent-keynote-recap-on-demand-videos-and-more-december-8-2025/

The week after AWS re:Invent builds on the excitement and energy of the event and is a good time to learn more and understand how the recent announcements can help you solve your challenges and unlock new opportunities. As usual, we have you covered with our top announcements of AWS re:Invent 2025 that you can learn all about here.

For me, one moment stood out above all the technical announcements: watching Rafi (Raphael Francis Quisumbing) from the Philippines receive the Now Go Build Award from Werner Vogels. Rafi has been an AWS Hero since 2015 and co-lead of AWS User Group Philippines since 2013. His dedication to building communities and empowering developers across the region embodies what this award represents. You can read more about Rafi on The Kernel. Congrats, Rafi!

The keynote recap: Agents, renaissance, and the developer’s role
This year’s AWS re:Invent keynotes painted a clear picture of where we’re headed.

Matt Garman emphasized that developers are “the heart of AWS” and that “freedom to invent” remains AWS’s core mission after 20 years. He focused on AI agents as the next inflection point: “AI assistants are starting to give way to AI agents that can perform tasks and automate on your behalf. This is where we’re starting to see material business returns from your AI investments.”

Swami Sivasubramanian highlighted the transformative moment we’re in: “For the first time in history, we can describe what we want to accomplish in natural language, and agents generate the plan. They write the code, call the necessary tools, and execute the complete solution.” AWS is building production-ready infrastructure that’s secure, reliable, and scalable—purpose-built for the non-deterministic nature of agents.

Peter DeSantis and Dave Brown reinforced that the core attributes AWS has obsessed over for 20 years—security, availability, performance, elasticity, cost, and agility—are more important than ever in the AI era. Dave Brown showcased Graviton and AWS’s custom silicon innovations that deliver these attributes at scale.

Werner Vogels delivered his final keynote after 14 years, introducing the concept of the “renaissance developer”—someone who is curious, thinks in systems, and communicates effectively. His message about AI and developer evolution resonated: “Will AI take my job? Maybe. Will AI make me obsolete? Absolutely not… if you evolve.” He emphasized that developers must be owners: “The work is yours, not that of the tools. You build it, you own it.”

You can also watch from keynotes, innovation talks to breakout sessions and more in the on-demand video page.

Innovations Talks

Breakout sessions — Topics Breakout sessions — Segments

Last week’s launches
Here are the launches that caught my attention not yet covered in our top announcements of AWS re:Invent 2025 post:

  • Kiro Autonomous Agent – Building on Kiro’s general availability in November with team features, AWS introduced an autonomous agent that maintains awareness across sessions, learns from pull requests and feedback, and handles bug triage and code coverage improvements spanning multiple repositories. “Orders of magnitude more efficient” than first-generation AI coding tools, Matt Garman said. Kiro is now Amazon’s standard AI development environment company-wide.
  • Multimodal Retrieval for Bedrock Knowledge Bases (GA) – Build AI-powered search and question-answering applications that work across text, images, audio, and video files. Developers can now ingest multimodal content with full control of parsing, chunking, embedding, and vector storage options, then send text or image queries to retrieve relevant segments across all media types.
  • AWS Interconnect – Multicloud (Preview) – Quickly establish private, secure, high-speed network connections with dedicated bandwidth and built-in resiliency between Amazon VPCs and other cloud environments. Starting in preview with Google Cloud as the first launch partner, with Microsoft Azure support coming in 2026.

See AWS What’s New for more launch news that I haven’t covered here. That’s all for this week. Check back next Monday for another Weekly Roundup!

Happy building!

Donnie

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Amazon Bedrock adds reinforcement fine-tuning simplifying how developers build smarter, more accurate AI models

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/improve-model-accuracy-with-reinforcement-fine-tuning-in-amazon-bedrock/

Organizations face a challenging trade-off when adapting AI models to their specific business needs: settle for generic models that produce average results, or tackle the complexity and expense of advanced model customization. Traditional approaches force a choice between poor performance with smaller models or the high costs of deploying larger model variants and managing complex infrastructure. Reinforcement fine-tuning is an advanced technique that trains models using feedback instead of massive labeled datasets, but implementing it typically requires specialized ML expertise, complicated infrastructure, and significant investment—with no guarantee of achieving the accuracy needed for specific use cases.

Today, we’re announcing reinforcement fine-tuning in Amazon Bedrock, a new model customization capability that creates smarter, more cost-effective models that learn from feedback and deliver higher-quality outputs for specific business needs. Reinforcement fine-tuning uses a feedback-driven approach where models improve iteratively based on reward signals, delivering 66% accuracy gains on average over base models.

Amazon Bedrock automates the reinforcement fine-tuning workflow, making this advanced model customization technique accessible to everyday developers without requiring deep machine learning (ML) expertise or large labeled datasets.

How reinforcement fine-tuning works
Reinforcement fine-tuning is built on top of reinforcement learning principles to address a common challenge: getting models to consistently produce outputs that align with business requirements and user preferences.

While traditional fine-tuning requires large, labeled datasets and expensive human annotation, reinforcement fine-tuning takes a different approach. Instead of learning from fixed examples, it uses reward functions to evaluate and judge which responses are considered good for particular business use cases. This teaches models to understand what makes a quality response without requiring massive amounts of pre-labeled training data, making advanced model customization in Amazon Bedrock more accessible and cost-effective.

Here are the benefits of using reinforcement fine-tuning in Amazon Bedrock:

  • Ease of use – Amazon Bedrock automates much of the complexity, making reinforcement fine-tuning more accessible to developers building AI applications. Models can be trained using existing API logs in Amazon Bedrock or by uploading datasets as training data, eliminating the need for labeled datasets or infrastructure setup.
  • Better model performance – Reinforcement fine-tuning improves model accuracy by 66% on average over base models, enabling optimization for price and performance by training smaller, faster, and more efficient model variants. This works with Amazon Nova 2 Lite model, improving quality and price performance for specific business needs, with support for additional models coming soon.
  • Security – Data remains within the secure AWS environment throughout the entire customization process, mitigating security and compliance concerns.

The capability supports two complementary approaches to provide flexibility for optimizing models:

  • Reinforcement Learning with Verifiable Rewards (RLVR) uses rule-based graders for objective tasks like code generation or math reasoning.
  • Reinforcement Learning from AI Feedback (RLAIF) employs AI-based judges for subjective tasks like instruction following or content moderation.

Getting started with reinforcement fine-tuning in Amazon Bedrock
Let’s walk through creating a reinforcement fine-tuning job.

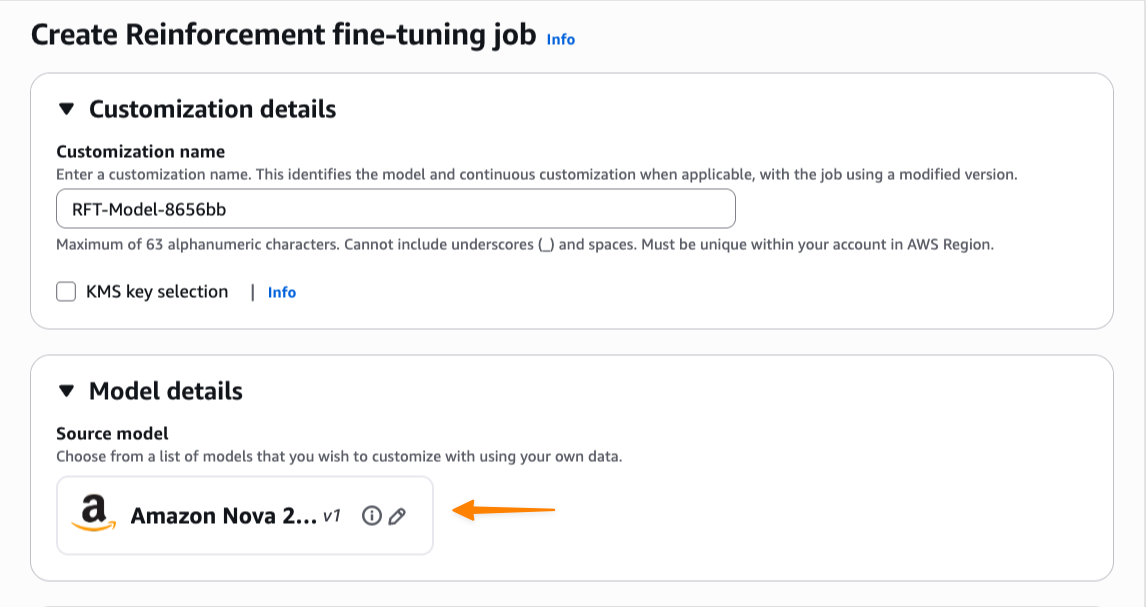
First, I access the Amazon Bedrock console. Then, I navigate to the Custom models page. I choose Create and then choose Reinforcement fine-tuning job.

I start by entering the name of this customization job and then select my base model. At launch, reinforcement fine-tuning supports Amazon Nova 2 Lite, with support for additional models coming soon.

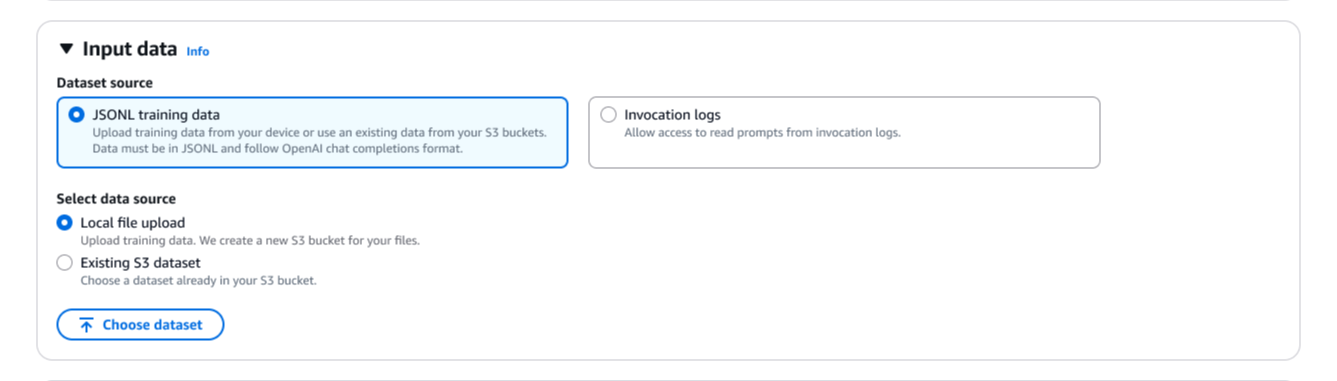
Next, I need to provide training data. I can use my stored invocation logs directly, eliminating the need to upload separate datasets. I can also upload new JSONL files or select existing datasets from Amazon Simple Storage Service (Amazon S3). Reinforcement fine-tuning automatically validates my training dataset and supports the OpenAI Chat Completions data format. If I provide invocation logs in the Amazon Bedrock invoke or converse format, Amazon Bedrock automatically converts them to the Chat Completions format.

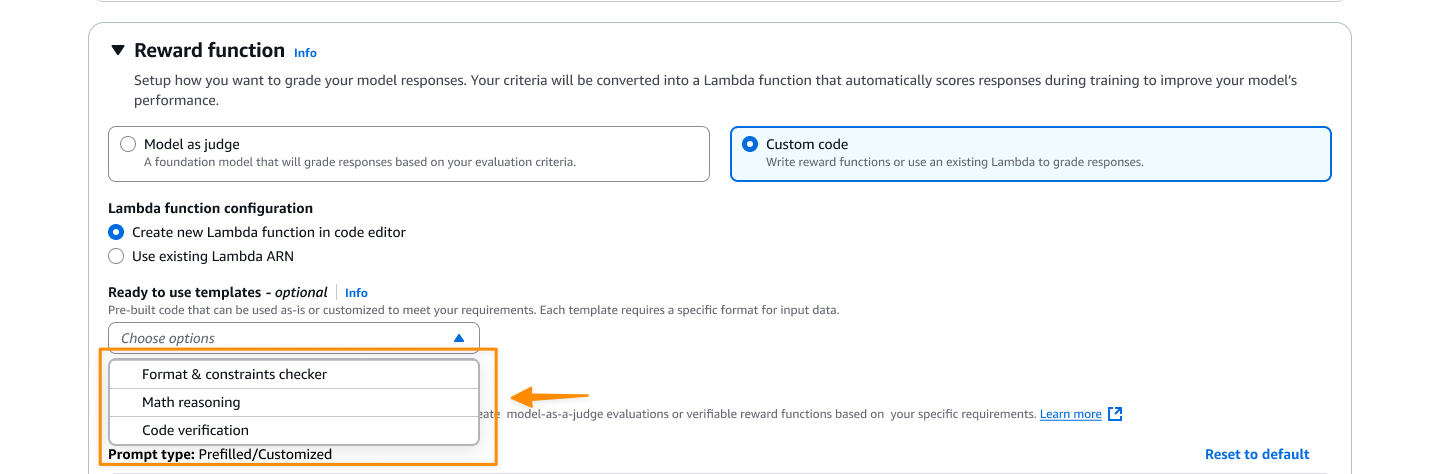
The reward function setup is where I define what constitutes a good response. I have two options here. For objective tasks, I can select Custom code and write custom Python code that gets executed through AWS Lambda functions. For more subjective evaluations, I can select Model as judge to use foundation models (FMs) as judges by providing evaluation instructions.

Here, I select Custom code, and I create a new Lambda function or use an existing one as a reward function. I can start with one of the provided templates and customize it for my specific needs.

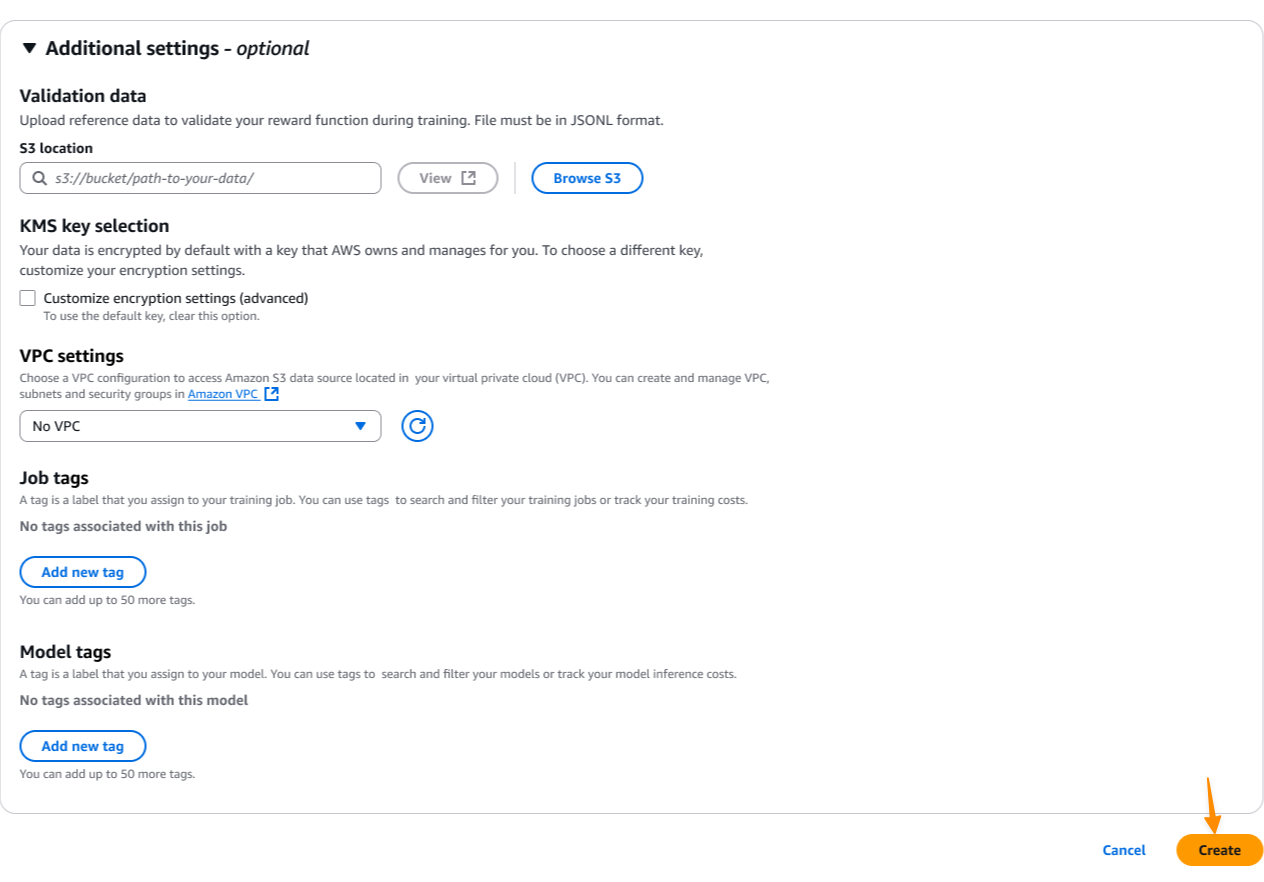
I can optionally modify default hyperparameters like learning rate, batch size, and epochs.

For enhanced security, I can configure virtual private cloud (VPC) settings and AWS Key Management Service (AWS KMS) encryption to meet my organization’s compliance requirements. Then, I choose Create to start the model customization job.

During the training process, I can monitor real-time metrics to understand how the model is learning. The training metrics dashboard shows key performance indicators including reward scores, loss curves, and accuracy improvements over time. These metrics help me understand whether the model is converging properly and if the reward function is effectively guiding the learning process.

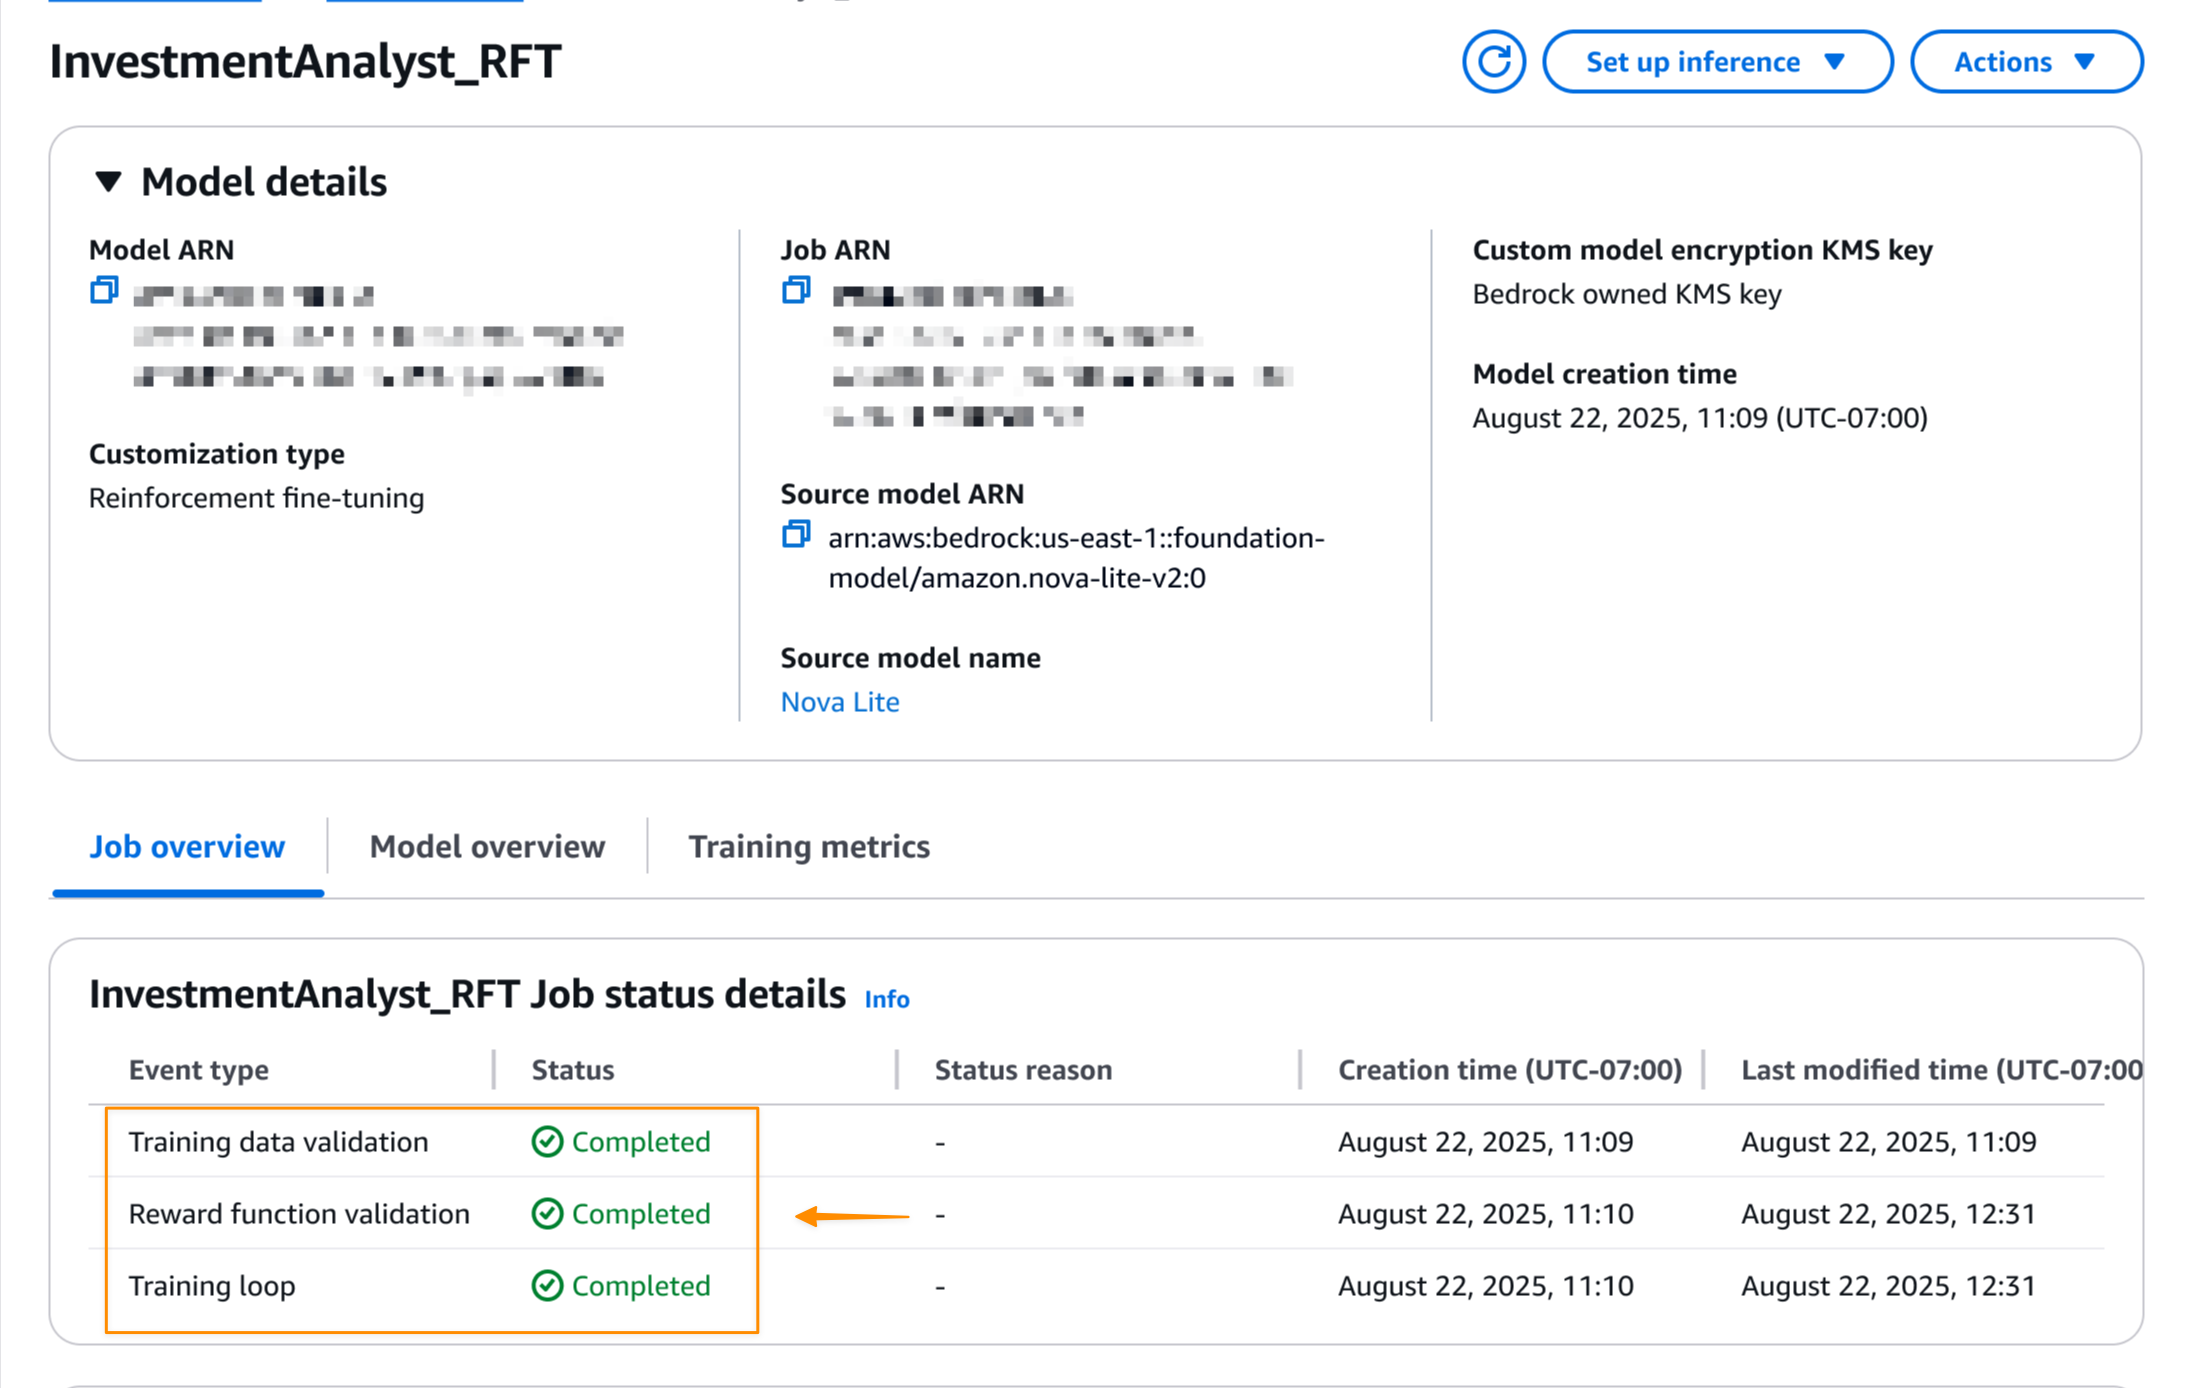
When the reinforcement fine-tuning job is completed, I can see the final job status on the Model details page.

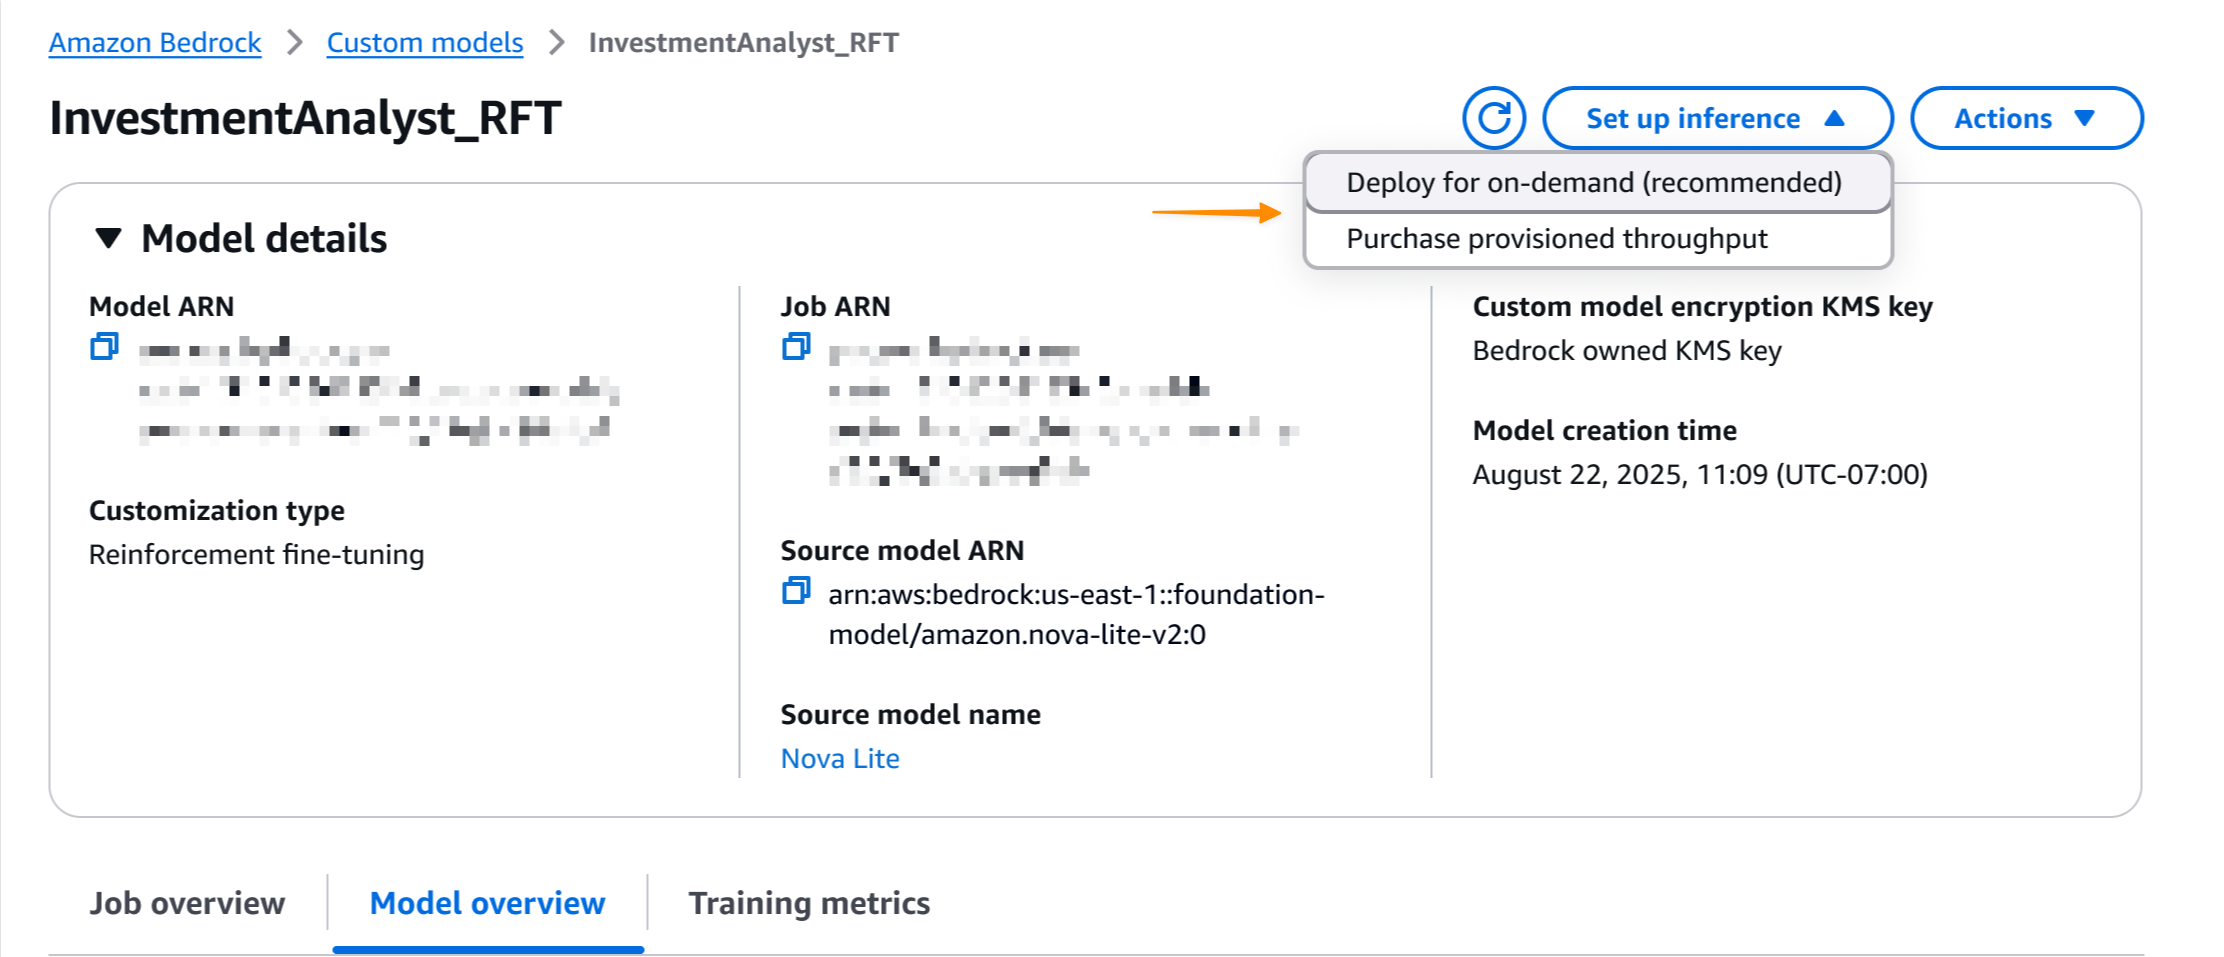
Once the job is completed, I can deploy the model with a single click. I select Set up inference, then choose Deploy for on-demand.

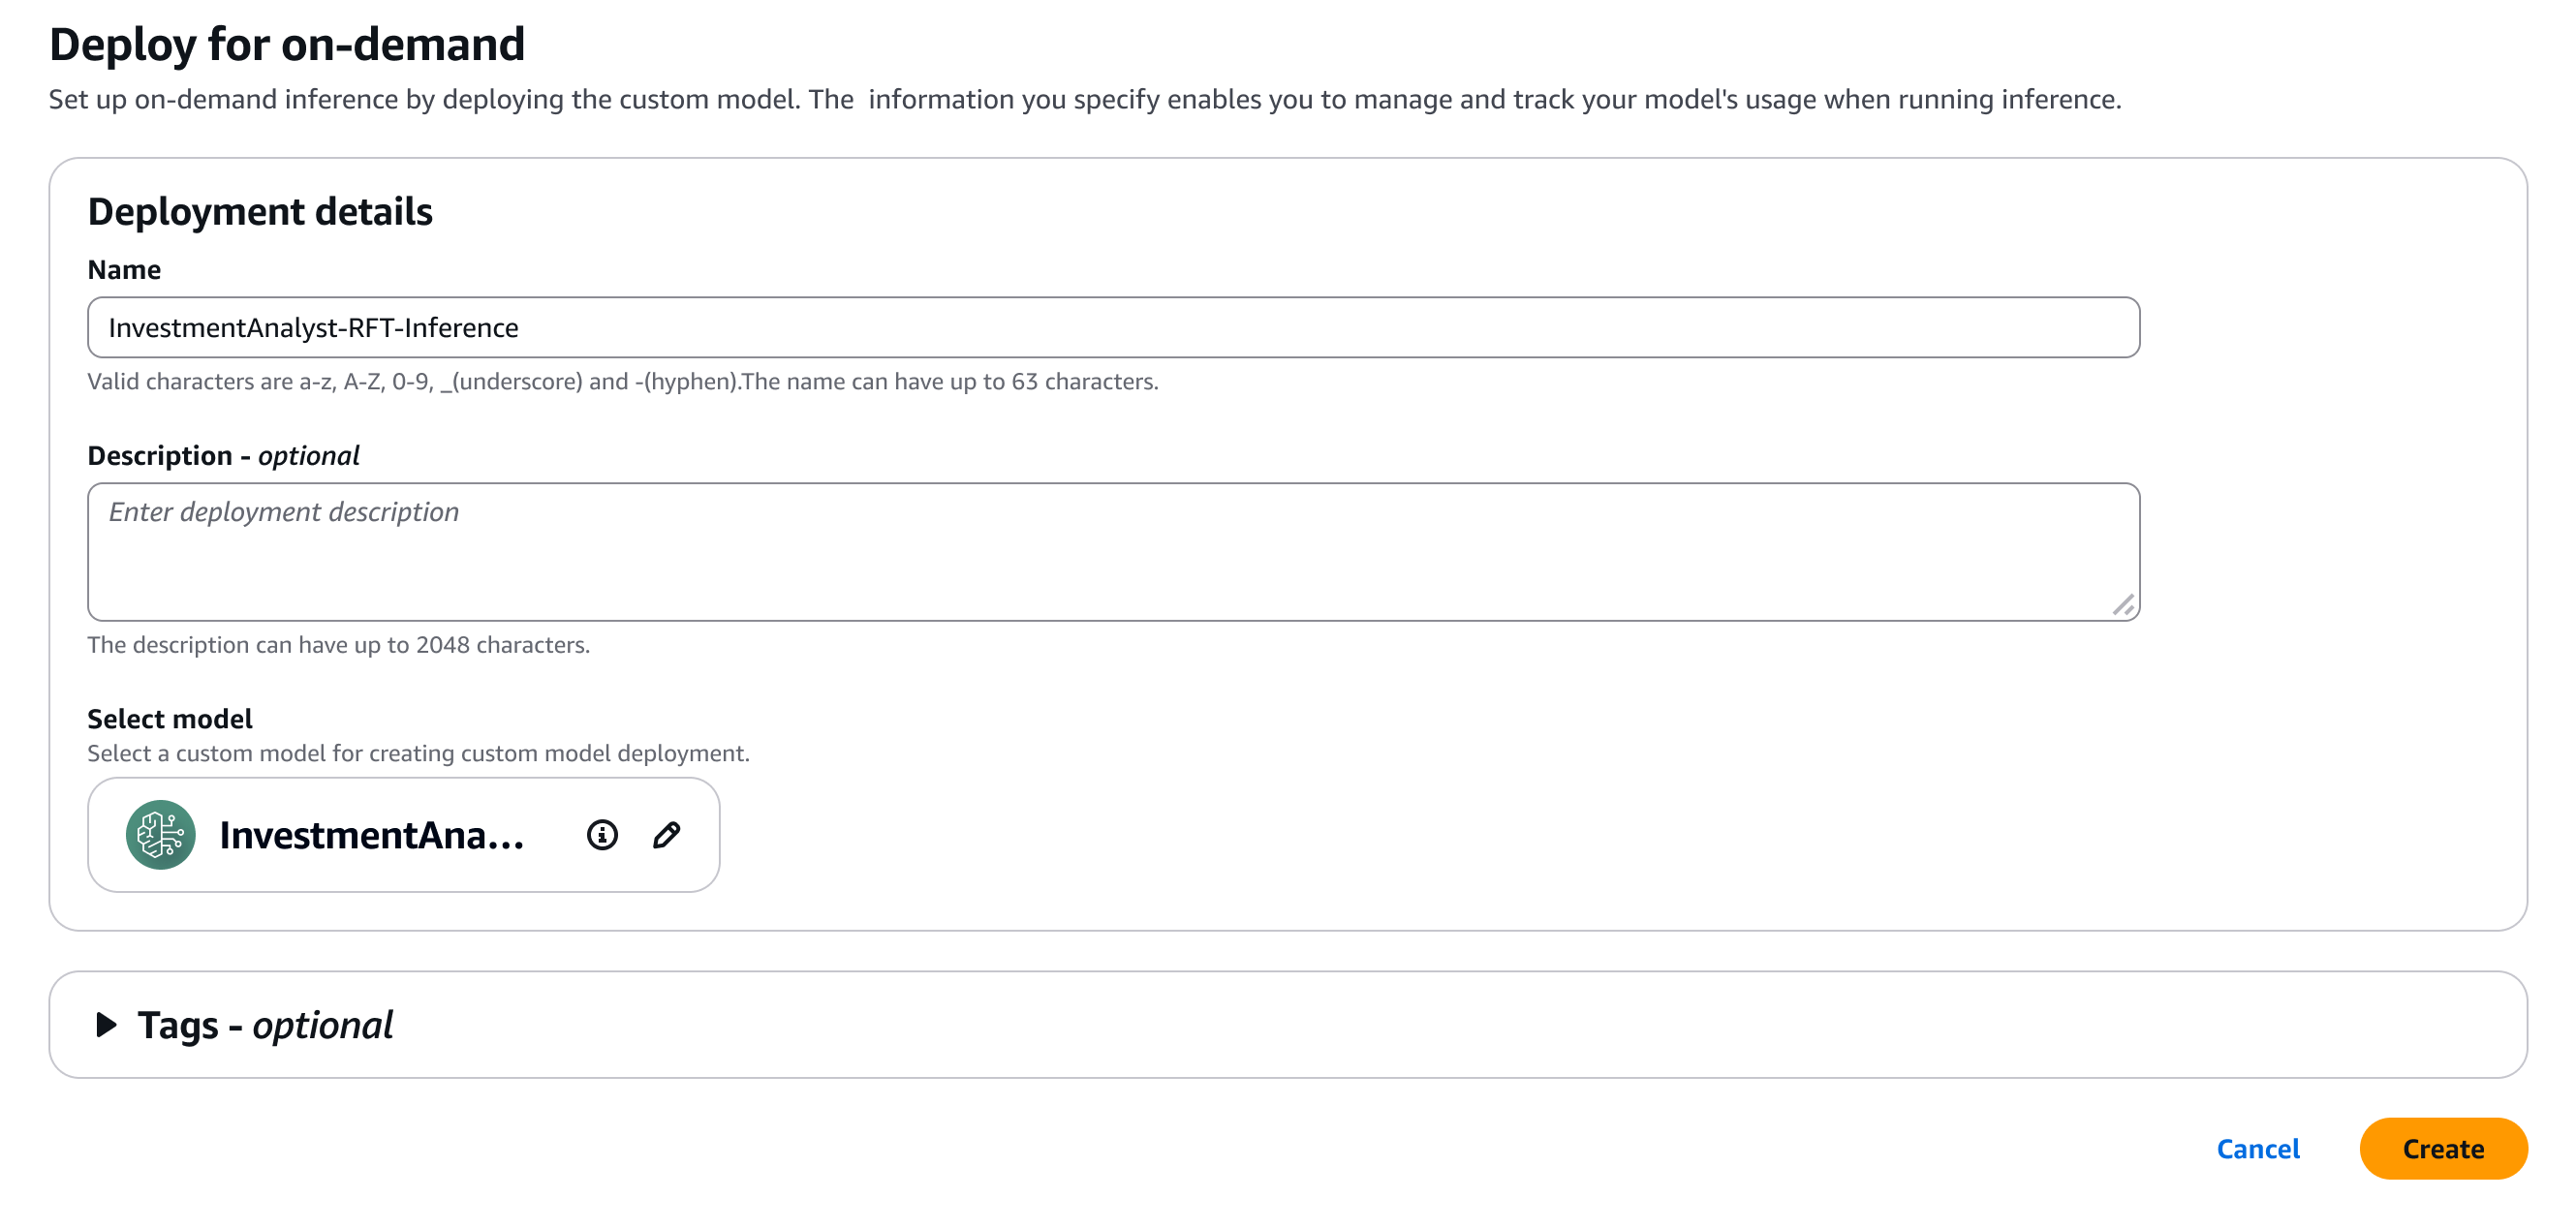
Here, I provide a few details for my model.

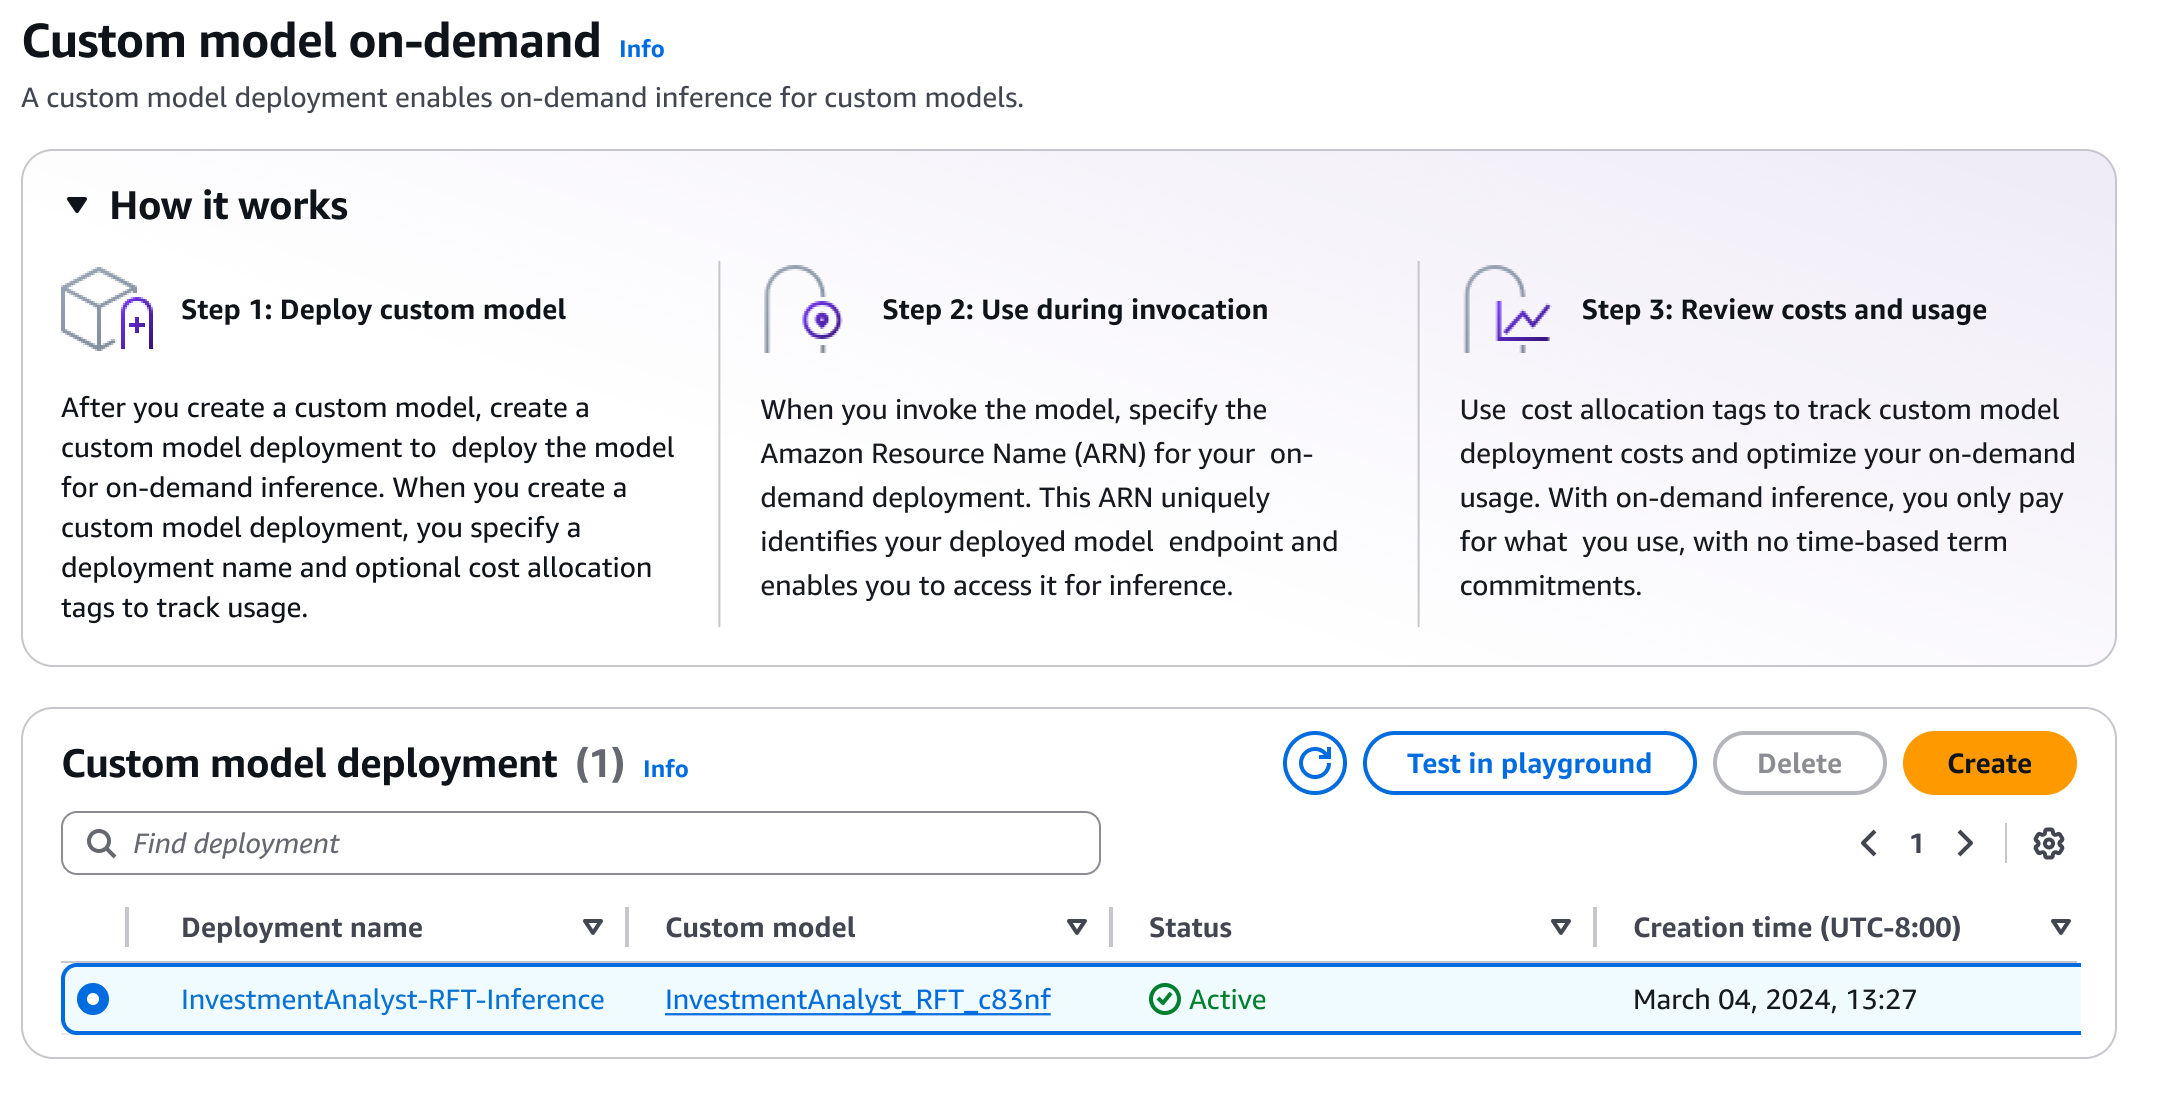
After deployment, I can quickly evaluate the model’s performance using the Amazon Bedrock playground. This helps me to test the fine-tuned model with sample prompts and compare its responses against the base model to validate the improvements. I select Test in playground.

The playground provides an intuitive interface for rapid testing and iteration, helping me confirm that the model meets my quality requirements before integrating it into production applications.

Interactive demo
Learn more by navigating an interactive demo of Amazon Bedrock reinforcement fine-tuning in action.

Additional things to know
Here are key points to note:

  • Templates — There are seven ready-to-use reward function templates covering common use cases for both objective and subjective tasks.
  • Pricing — To learn more about pricing, refer to the Amazon Bedrock pricing page.
  • Security — Training data and custom models remain private and aren’t used to improve FMs for public use. It supports VPC and AWS KMS encryption for enhanced security.

Get started with reinforcement fine-tuning by visiting the reinforcement fine-tuning documentation and by accessing the Amazon Bedrock console.

Happy building!
Donnie

Amazon CloudWatch introduces unified data management and analytics for operations, security, and compliance

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-cloudwatch-introduces-unified-data-management-and-analytics-for-operations-security-and-compliance/

Today we’re expanding Amazon CloudWatch capabilities to unify and manage log data across operational, security, and compliance use cases with flexible and powerful analytics in one place and with reduced data duplication and costs.

This enhancement means that CloudWatch can automatically normalize and process data to offer consistency across sources with built-in support for Open Cybersecurity Schema Framework (OCSF) and Open Telemetry (OTel) formats, so you can focus on analytics and insights. CloudWatch also introduces Apache Iceberg compatible access to your data through Amazon Simple Storage Service (Amazon S3) Tables, so that you can run analytics, not only locally but also using Amazon Athena, Amazon SageMaker Unified Studio, or any other Iceberg-compatible tool.

You can also correlate your operational data in CloudWatch with other business data from your preferred tools to correlate with other data. This unified approach streamlines management and provides comprehensive correlation across security, operational, and business use cases.

Here are the detailed enhancements:

  • Streamline data ingestion and normalization – CloudWatch automatically collects AWS vended logs across accounts and AWS Regions, integrating with AWS Organizations from AWS services including AWS CloudTrail, Amazon Virtual Private Cloud (Amazon VPC) Flow Logs, AWS WAF access logs, Amazon Route 53 resolver logs, and pre-built connectors for third-party sources such as endpoint (CrowdStrike, SentinelOne), identity (Okta, Entra ID), cloud security (Wiz), network security (Zscaler, Palo Alto Networks), productivity and collaboration (Microsoft Office 365, Windows Event Logs, and GitHub), along with IT service manager with ServiceNow CMBD. To normalize and process your data as they are being ingested, CloudWatch offers managed OCSF conversion for various AWS and third-party data sources and other processors such ad Grok for custom parsing, field-level operations, and string manipulations.
  • Reduce costly log data management – CloudWatch consolidates log management into a single service with built-in governance capabilities without storing and maintaining multiple copies of the same data across different tools and data stores. The unified data store of CloudWatch eliminates the need for complex ETL pipelines and reduces your operational costs and management overhead needed to maintain multiple separate data stores and tools.
  • Discover business insights from log data – You can run queries in CloudWatch using natural language queries and popular query languages such as LogsQL, PPL, and SQL through a single interface, or query your data using your preferred analytics tools through Apache Iceberg-compatible tables. The new Facets interface gives you intuitive filtering by source, application, account, region, and log type, which you can use to run queries across log groups of multiple AWS accounts and Regions with intelligent parameter inference.

In the next sections we explore the new log management and analytics features of the CloudWatch Logs!

1. Data discovery and management by data sources and types

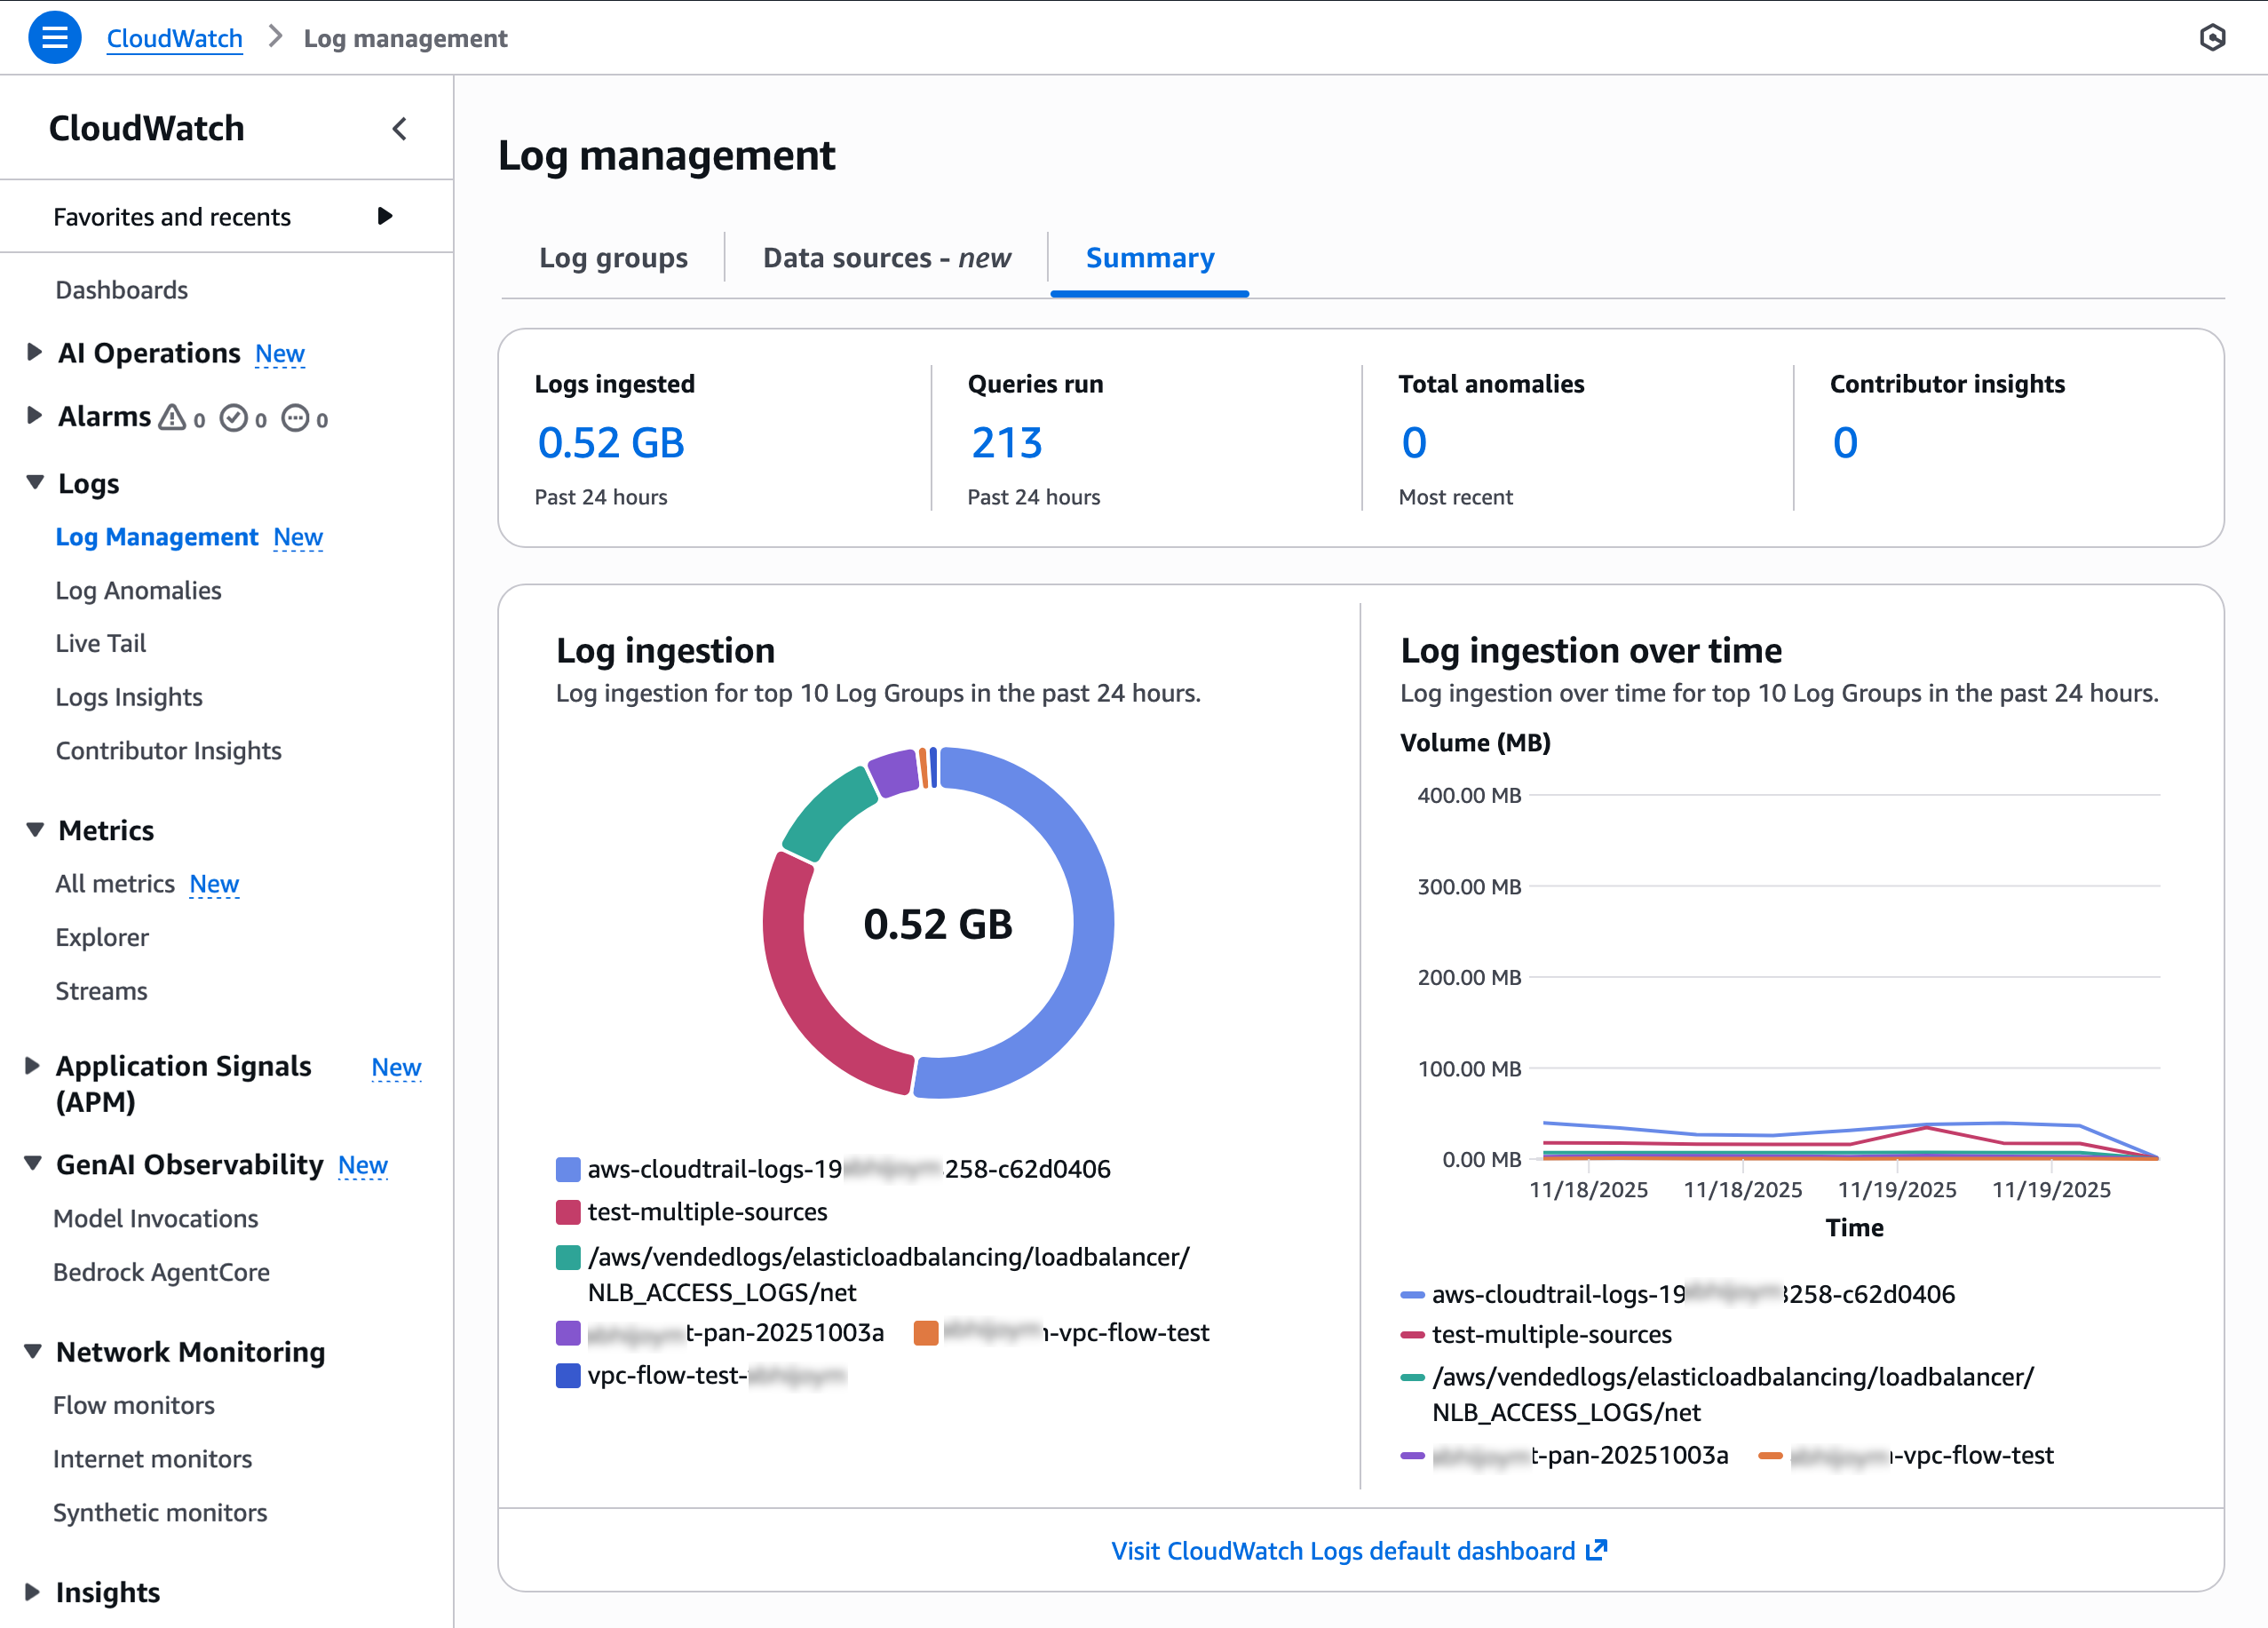
You can see a high-level overview of logs and all data sources with a new Logs Management View in the CloudWatch console. To get started, go to the CloudWatch console and choose Log Management under the Logs menu in the left navigation pane. In the Summary tab, you can observe your logs data sources and types, insights into how your log groups are doing across ingestion, and anomalies.

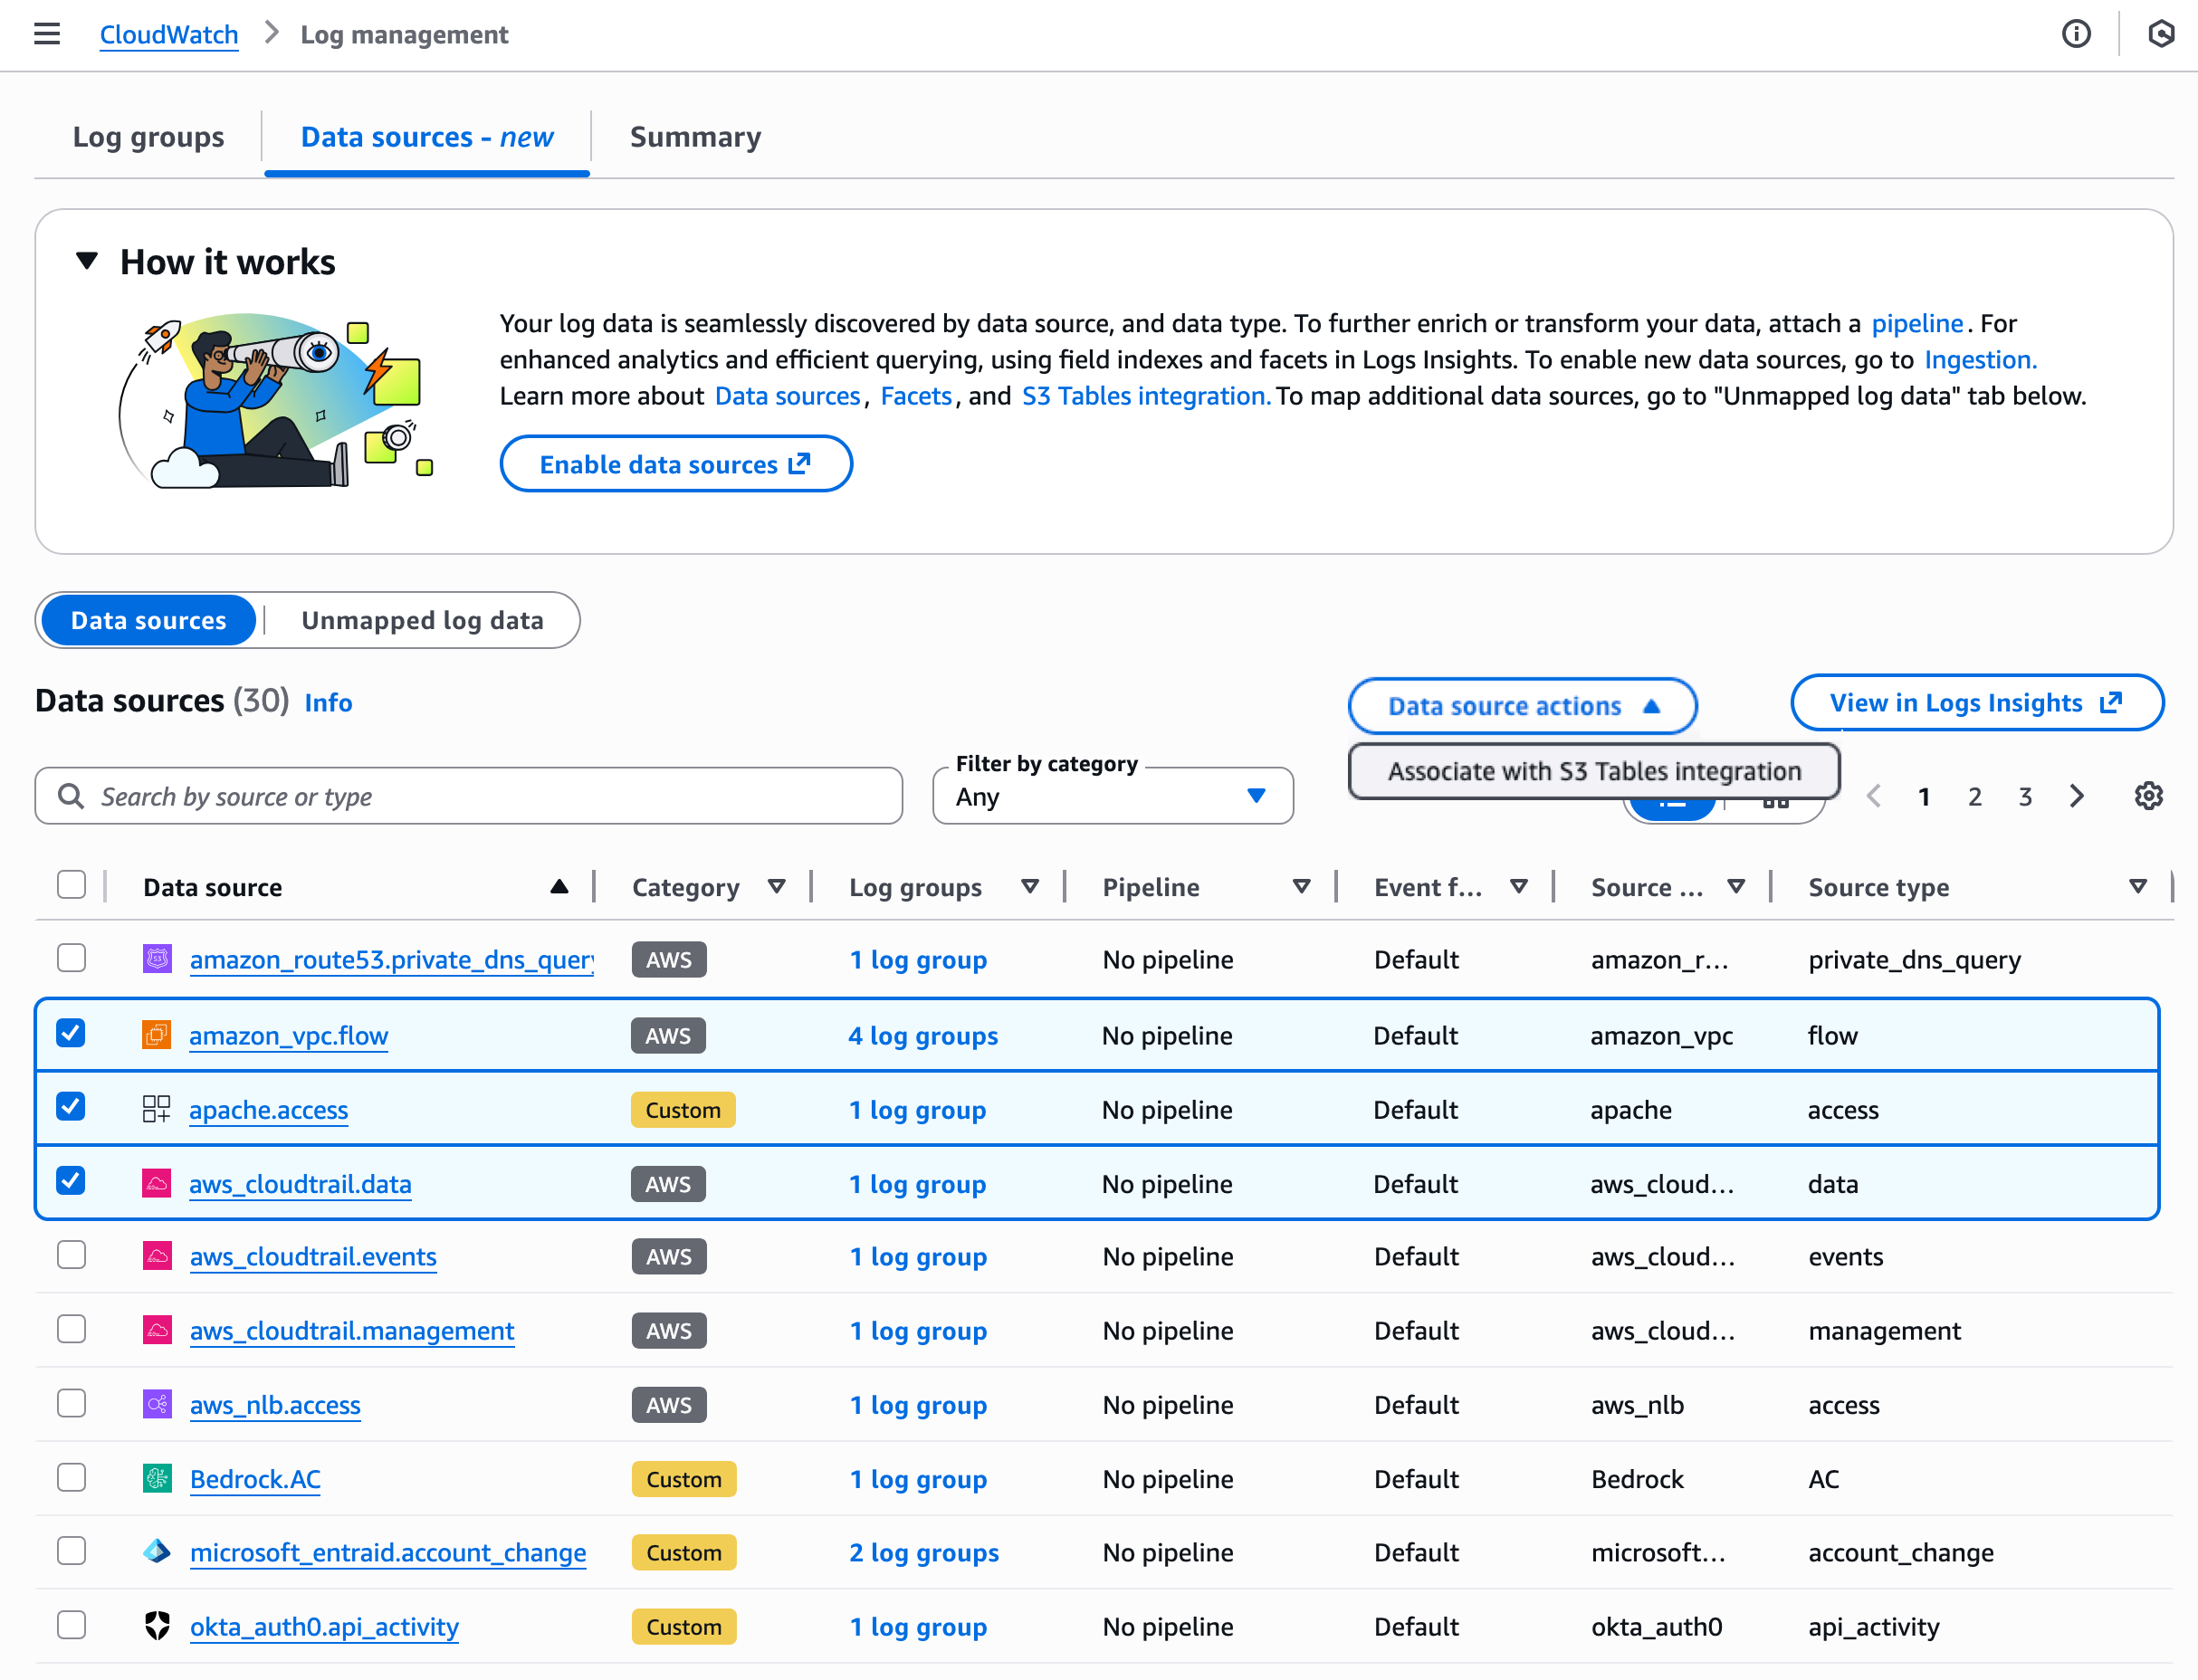
Choose the Data sources tab to find and manage your log data by data sources, types, and fields. CloudWatch ingests and automatically categorizes data sources by AWS services, third-party, or custom sources such as application logs.

Choose the Data source actions to integrate S3 Tables to make future logs for selected data sources. You have the flexibility to analyze the logs through Athena and Amazon Redshift and other query engines such as Spark using Iceberg compatible access patterns. With this integration, logs from CloudWatch are available in a read-only aws-cloudwatch S3 Tables bucket.

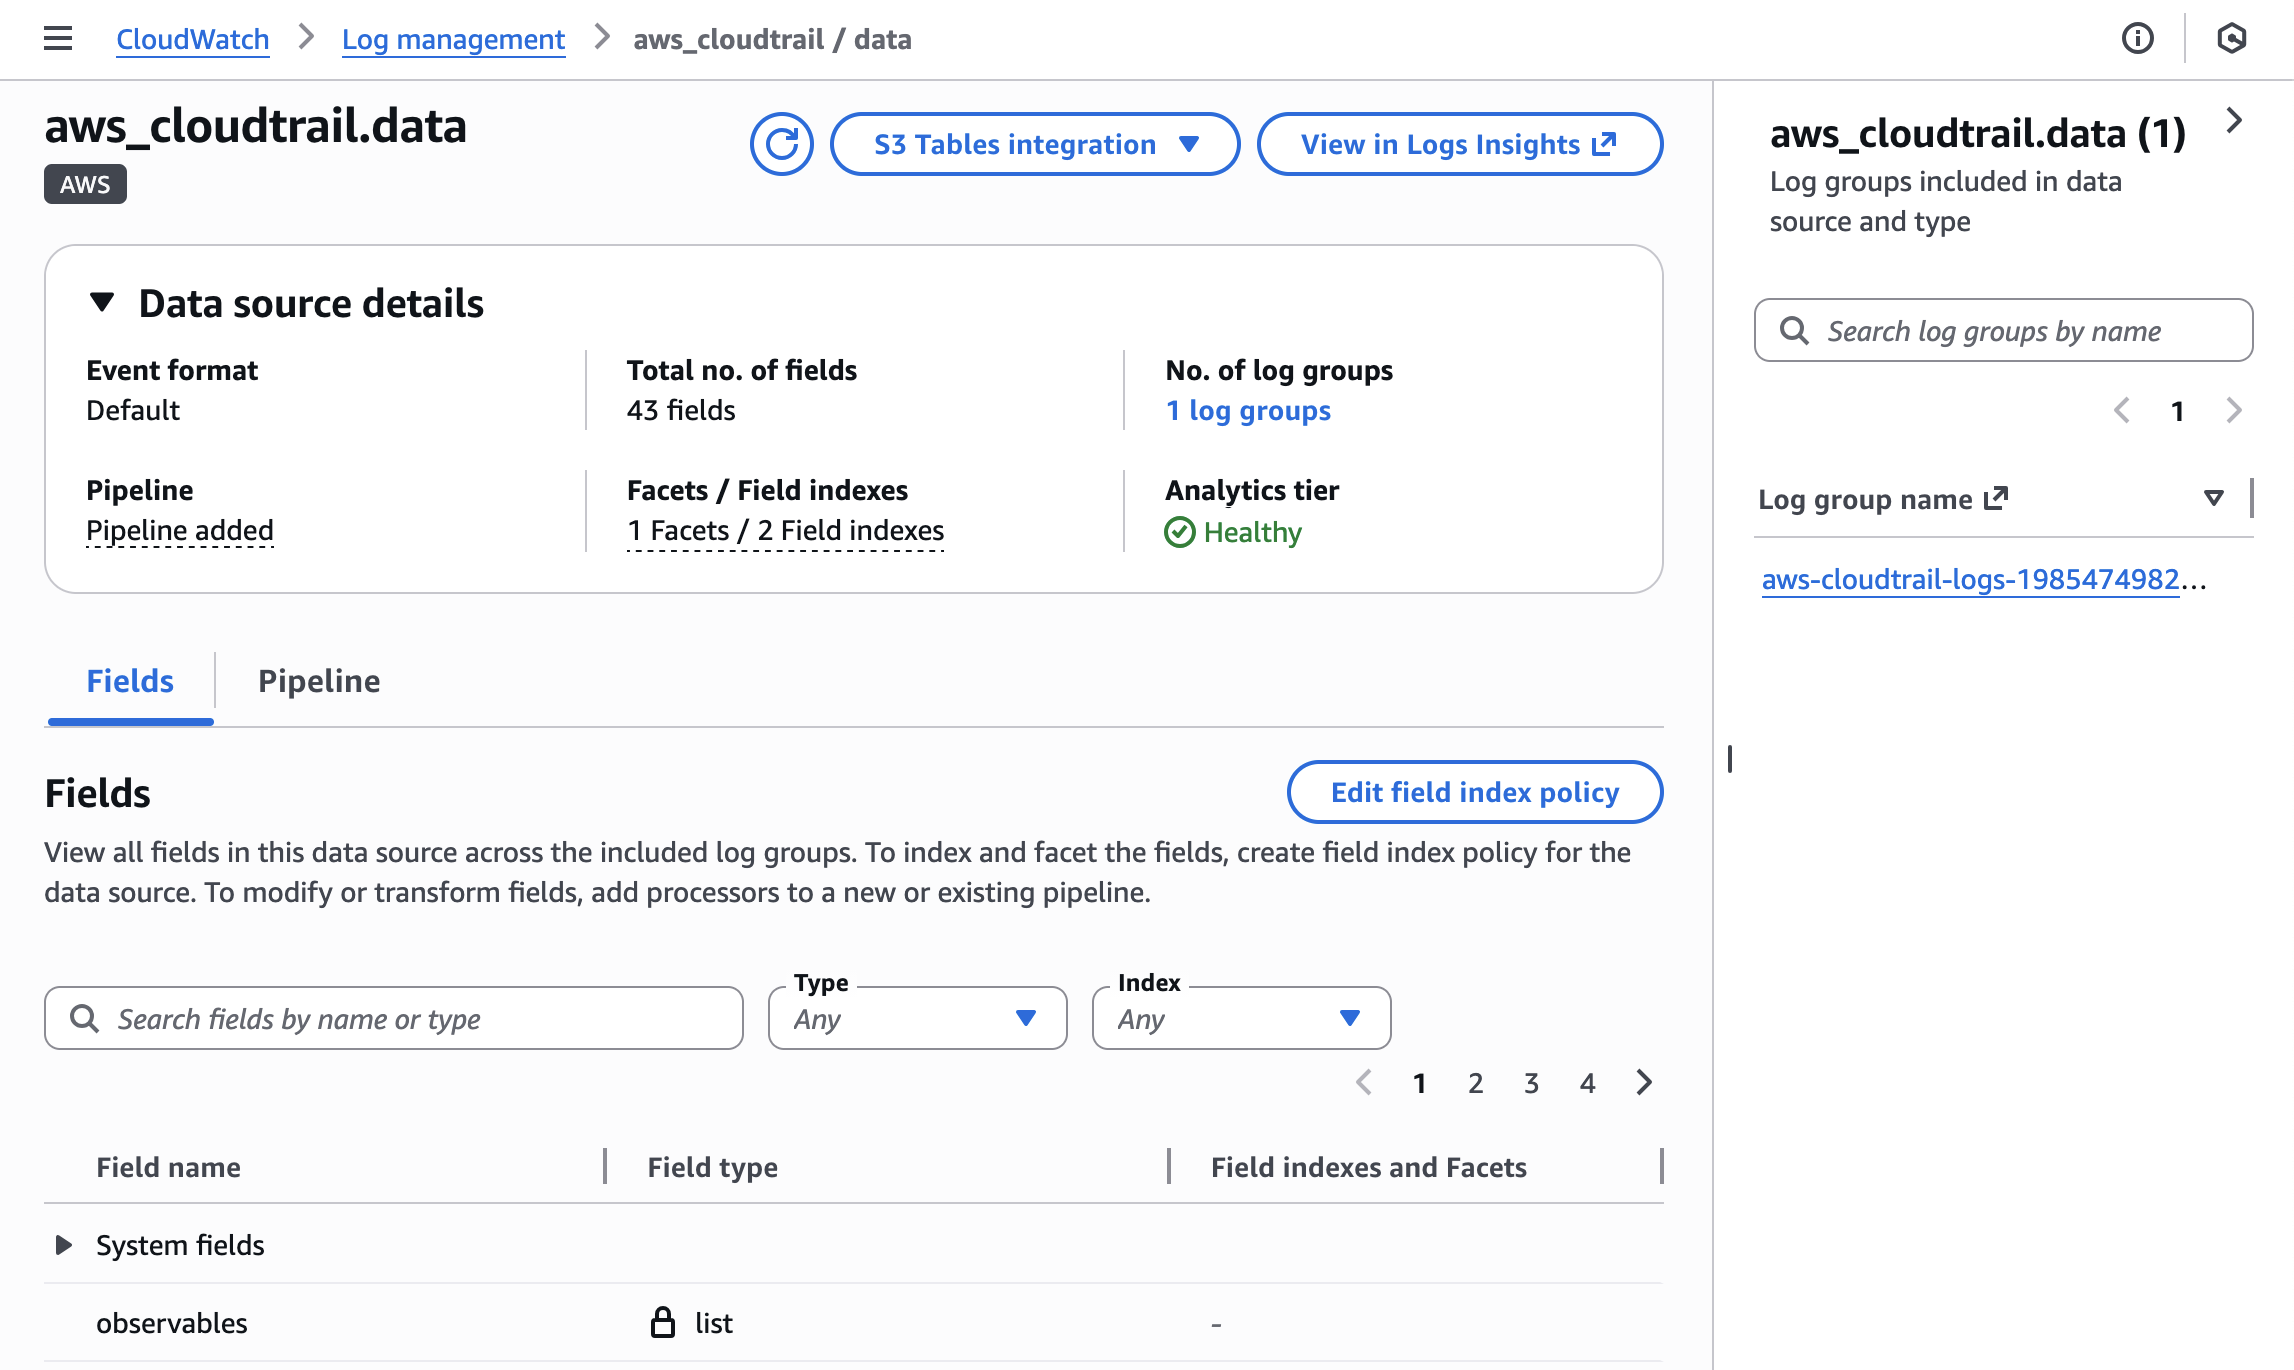
When you choose a specific data source such as CloudTrail data, you can view the details of the data source that includes information regarding data format, pipeline, facets/field indexes, S3 Tables association, and the number of logs with that data source. You can observe all log groups included in this data source and type and edit a source/type field index policy using the new schema support.

To learn more about how to manage your data sources and index policy, visit Data sources in the Amazon CloudWatch Logs User Guide.

2. Ingestion and transformation using CloudWatch pipelines

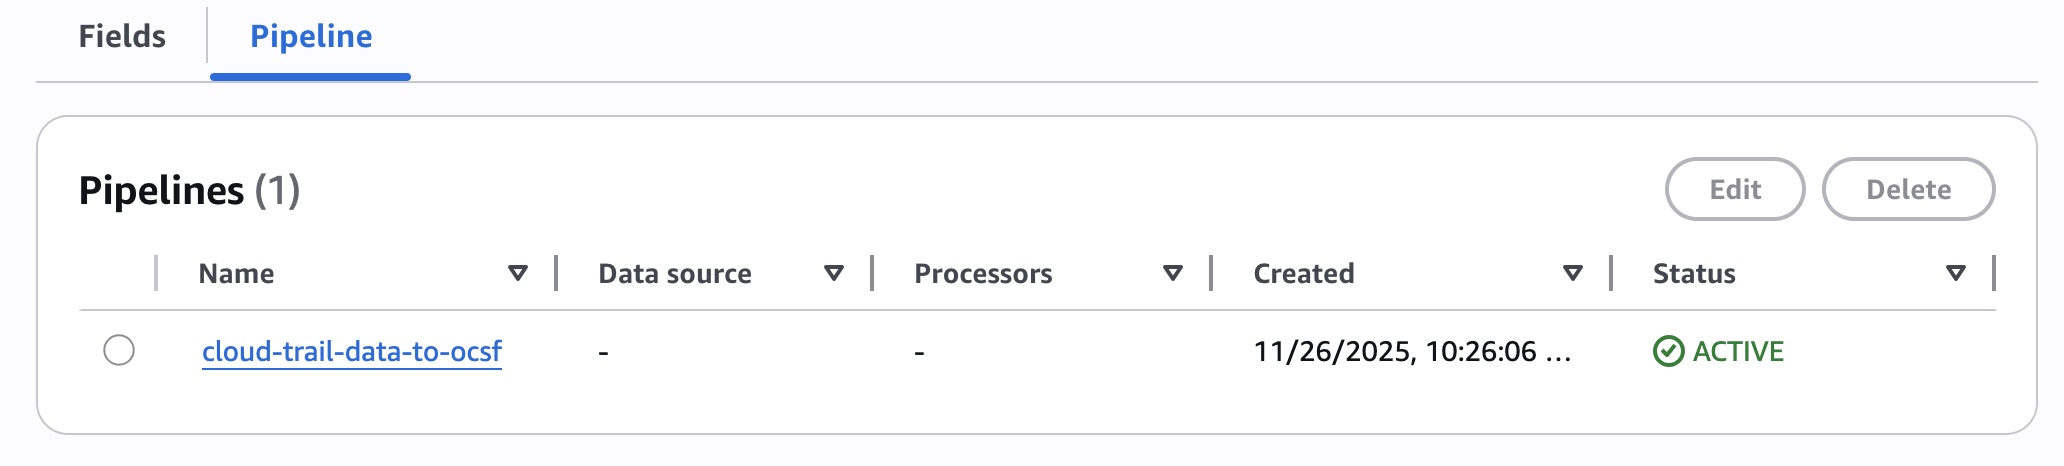
You can create pipelines to streamline collecting, transforming, and routing telemetry and security data while standardizing data formats to optimize observability and security data management. The new pipeline feature of CloudWatch connects data from a catalogue of data sources, so that you can add and configure pipeline processors from a library to parse, enrich, and standardize data.

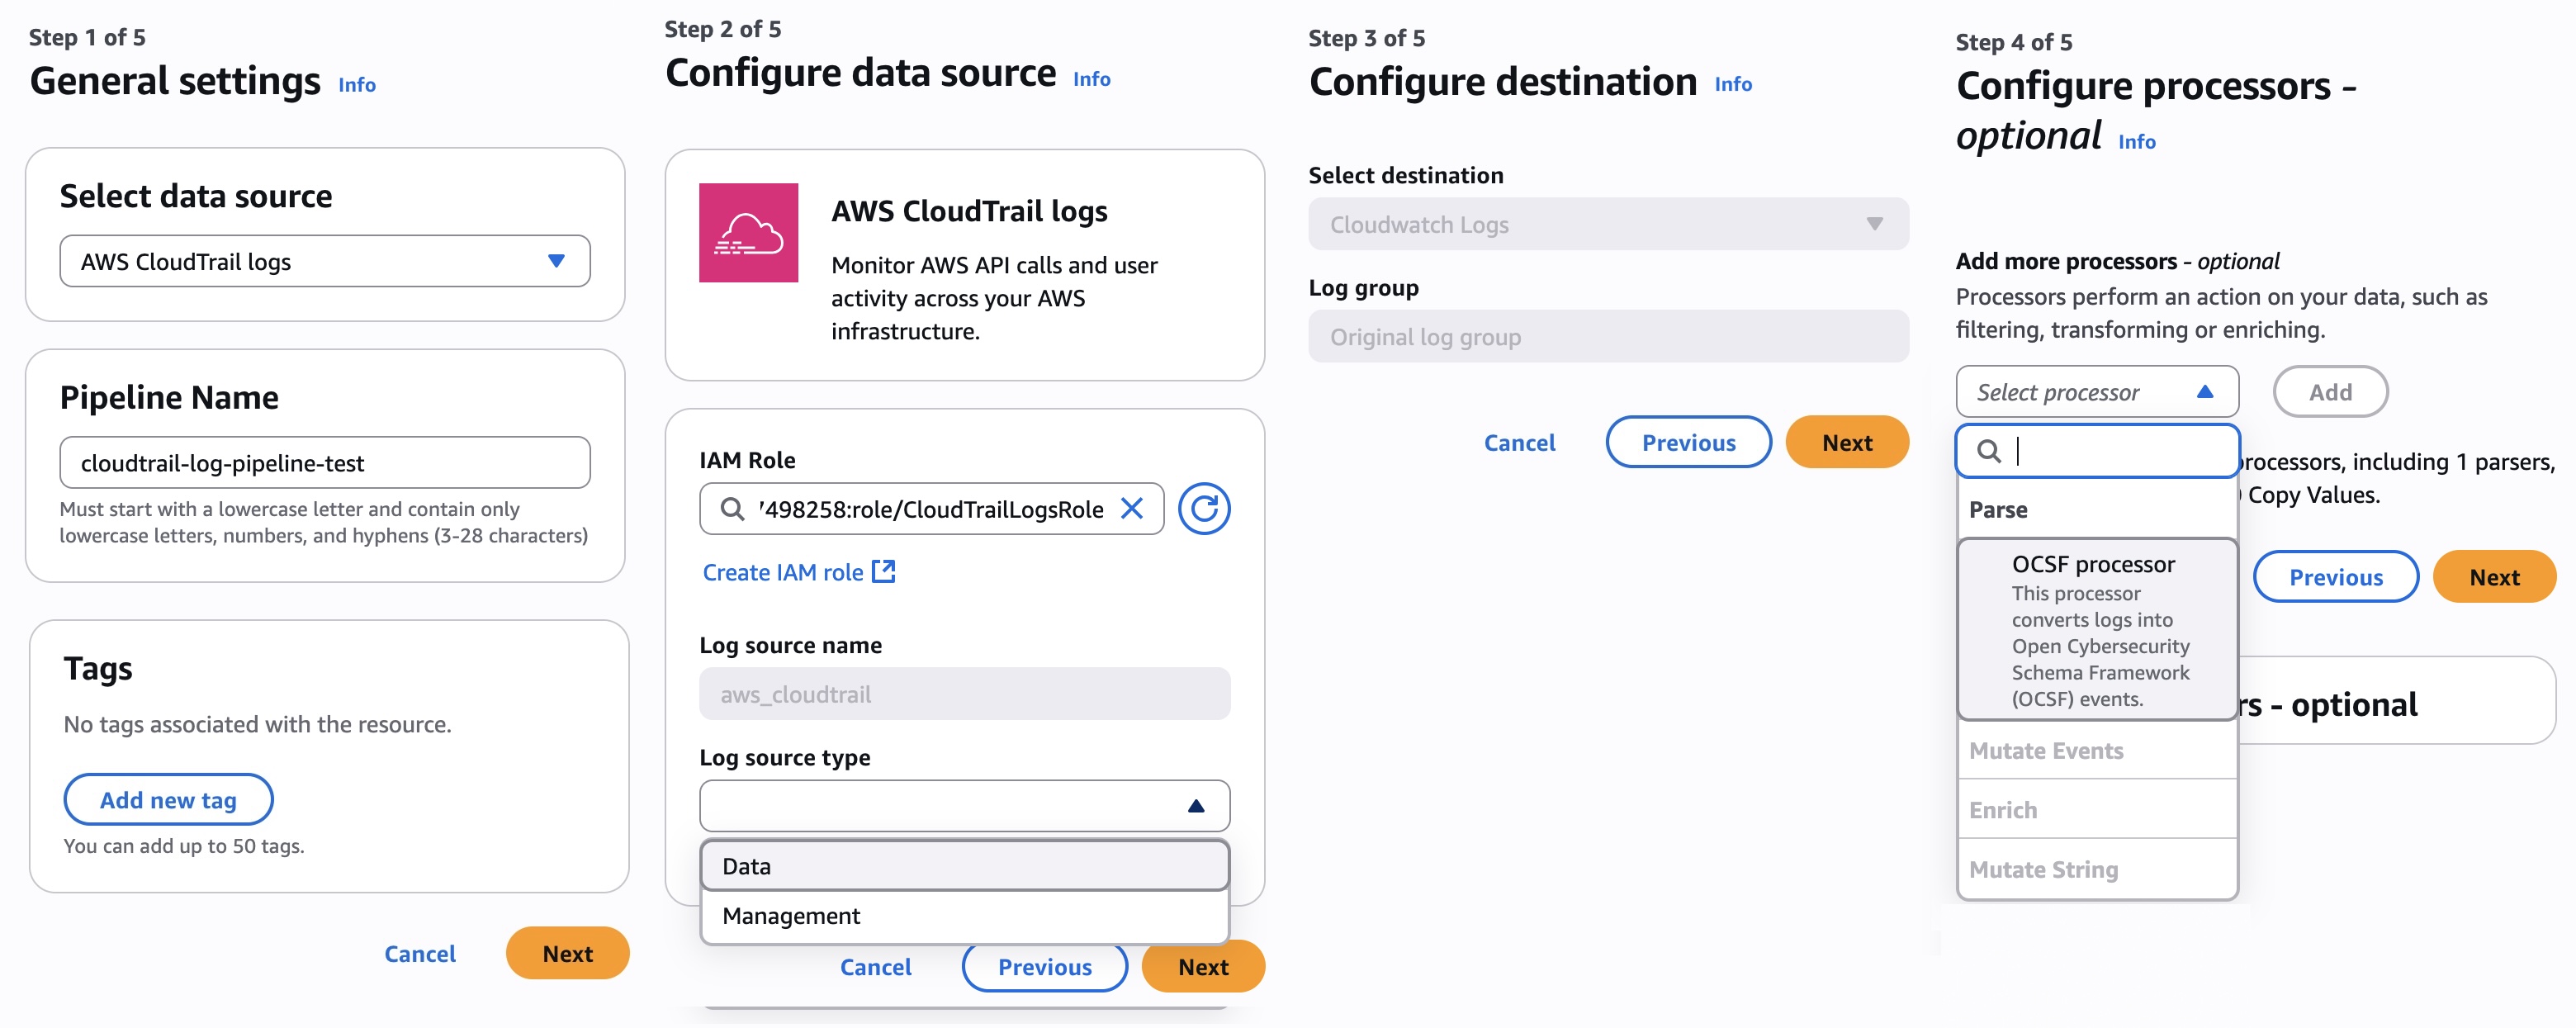
In the Pipeline tab, choose Add pipeline. It shows you the pipeline configuration wizard. This wizard guides you through five steps where you can choose the data source and other source details such as log source types, configure destination, configure up to 19 processors to perform an action on your data (such as filtering, transforming, or enriching), and finally review and deploy the pipeline.

You also have the option to create pipelines through the new Ingestion experience in CloudWatch. To learn more about how to set up and manage the pipelines, visit Pipelines in the Amazon CloudWatch Logs User Guide.

3. Enhanced analytics and querying based on data sources

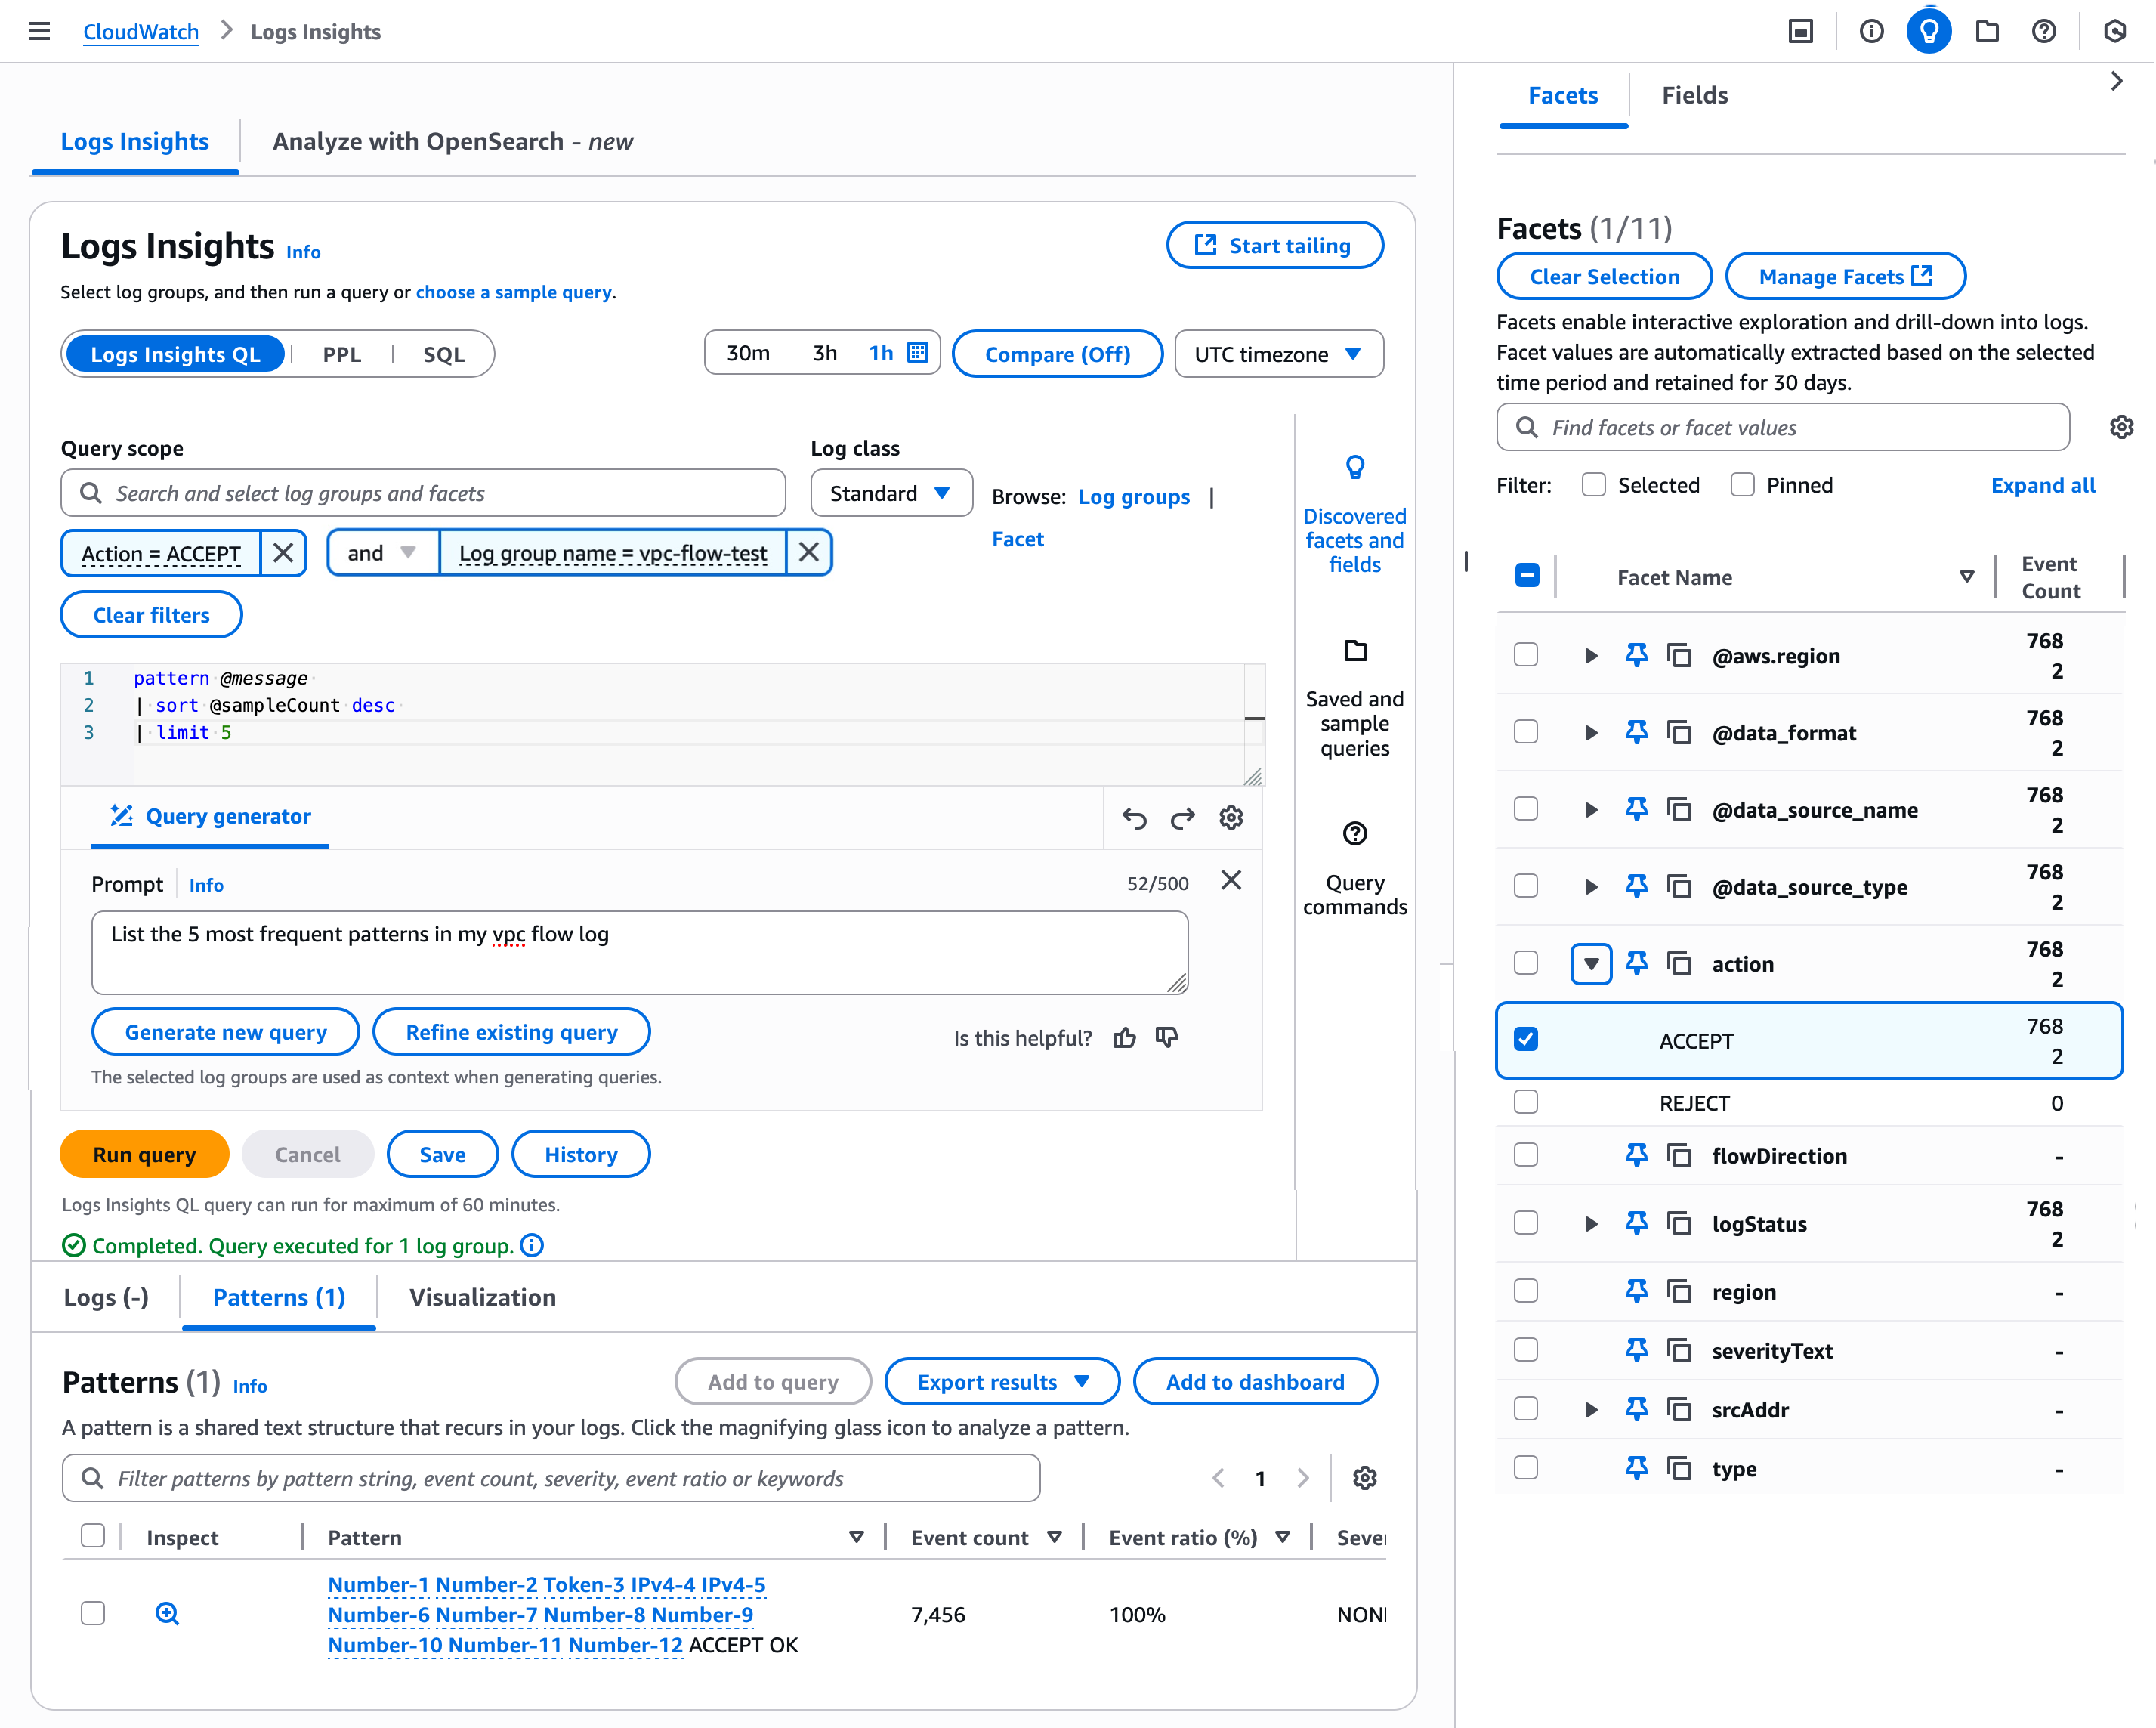
You can enhance analytics with support for Facets and querying based on data sources. Facets enable interactive exploration and drill-down into logs and their values are automatically extracted based on the selected time period.

Choose the Facets tab in the Log Insights under the Logs menu in the left navigation pane. You can view available facets and values that appear in the panel. Choose one or more facets and values to interactively explore your data. I choose Facets regarding a VPC Flow Logs group and action, query to list the five most frequent patterns in my VPC Flow Logs through the AI query generator, and get the result patterns.

You can save your query with the selected Facets and values that you have specified. When you next choose your saved query, the logs to be queried have the pre-specified facets and values. To learn more about Facet management, visit Facets in the CloudWatch Logs User Guide.

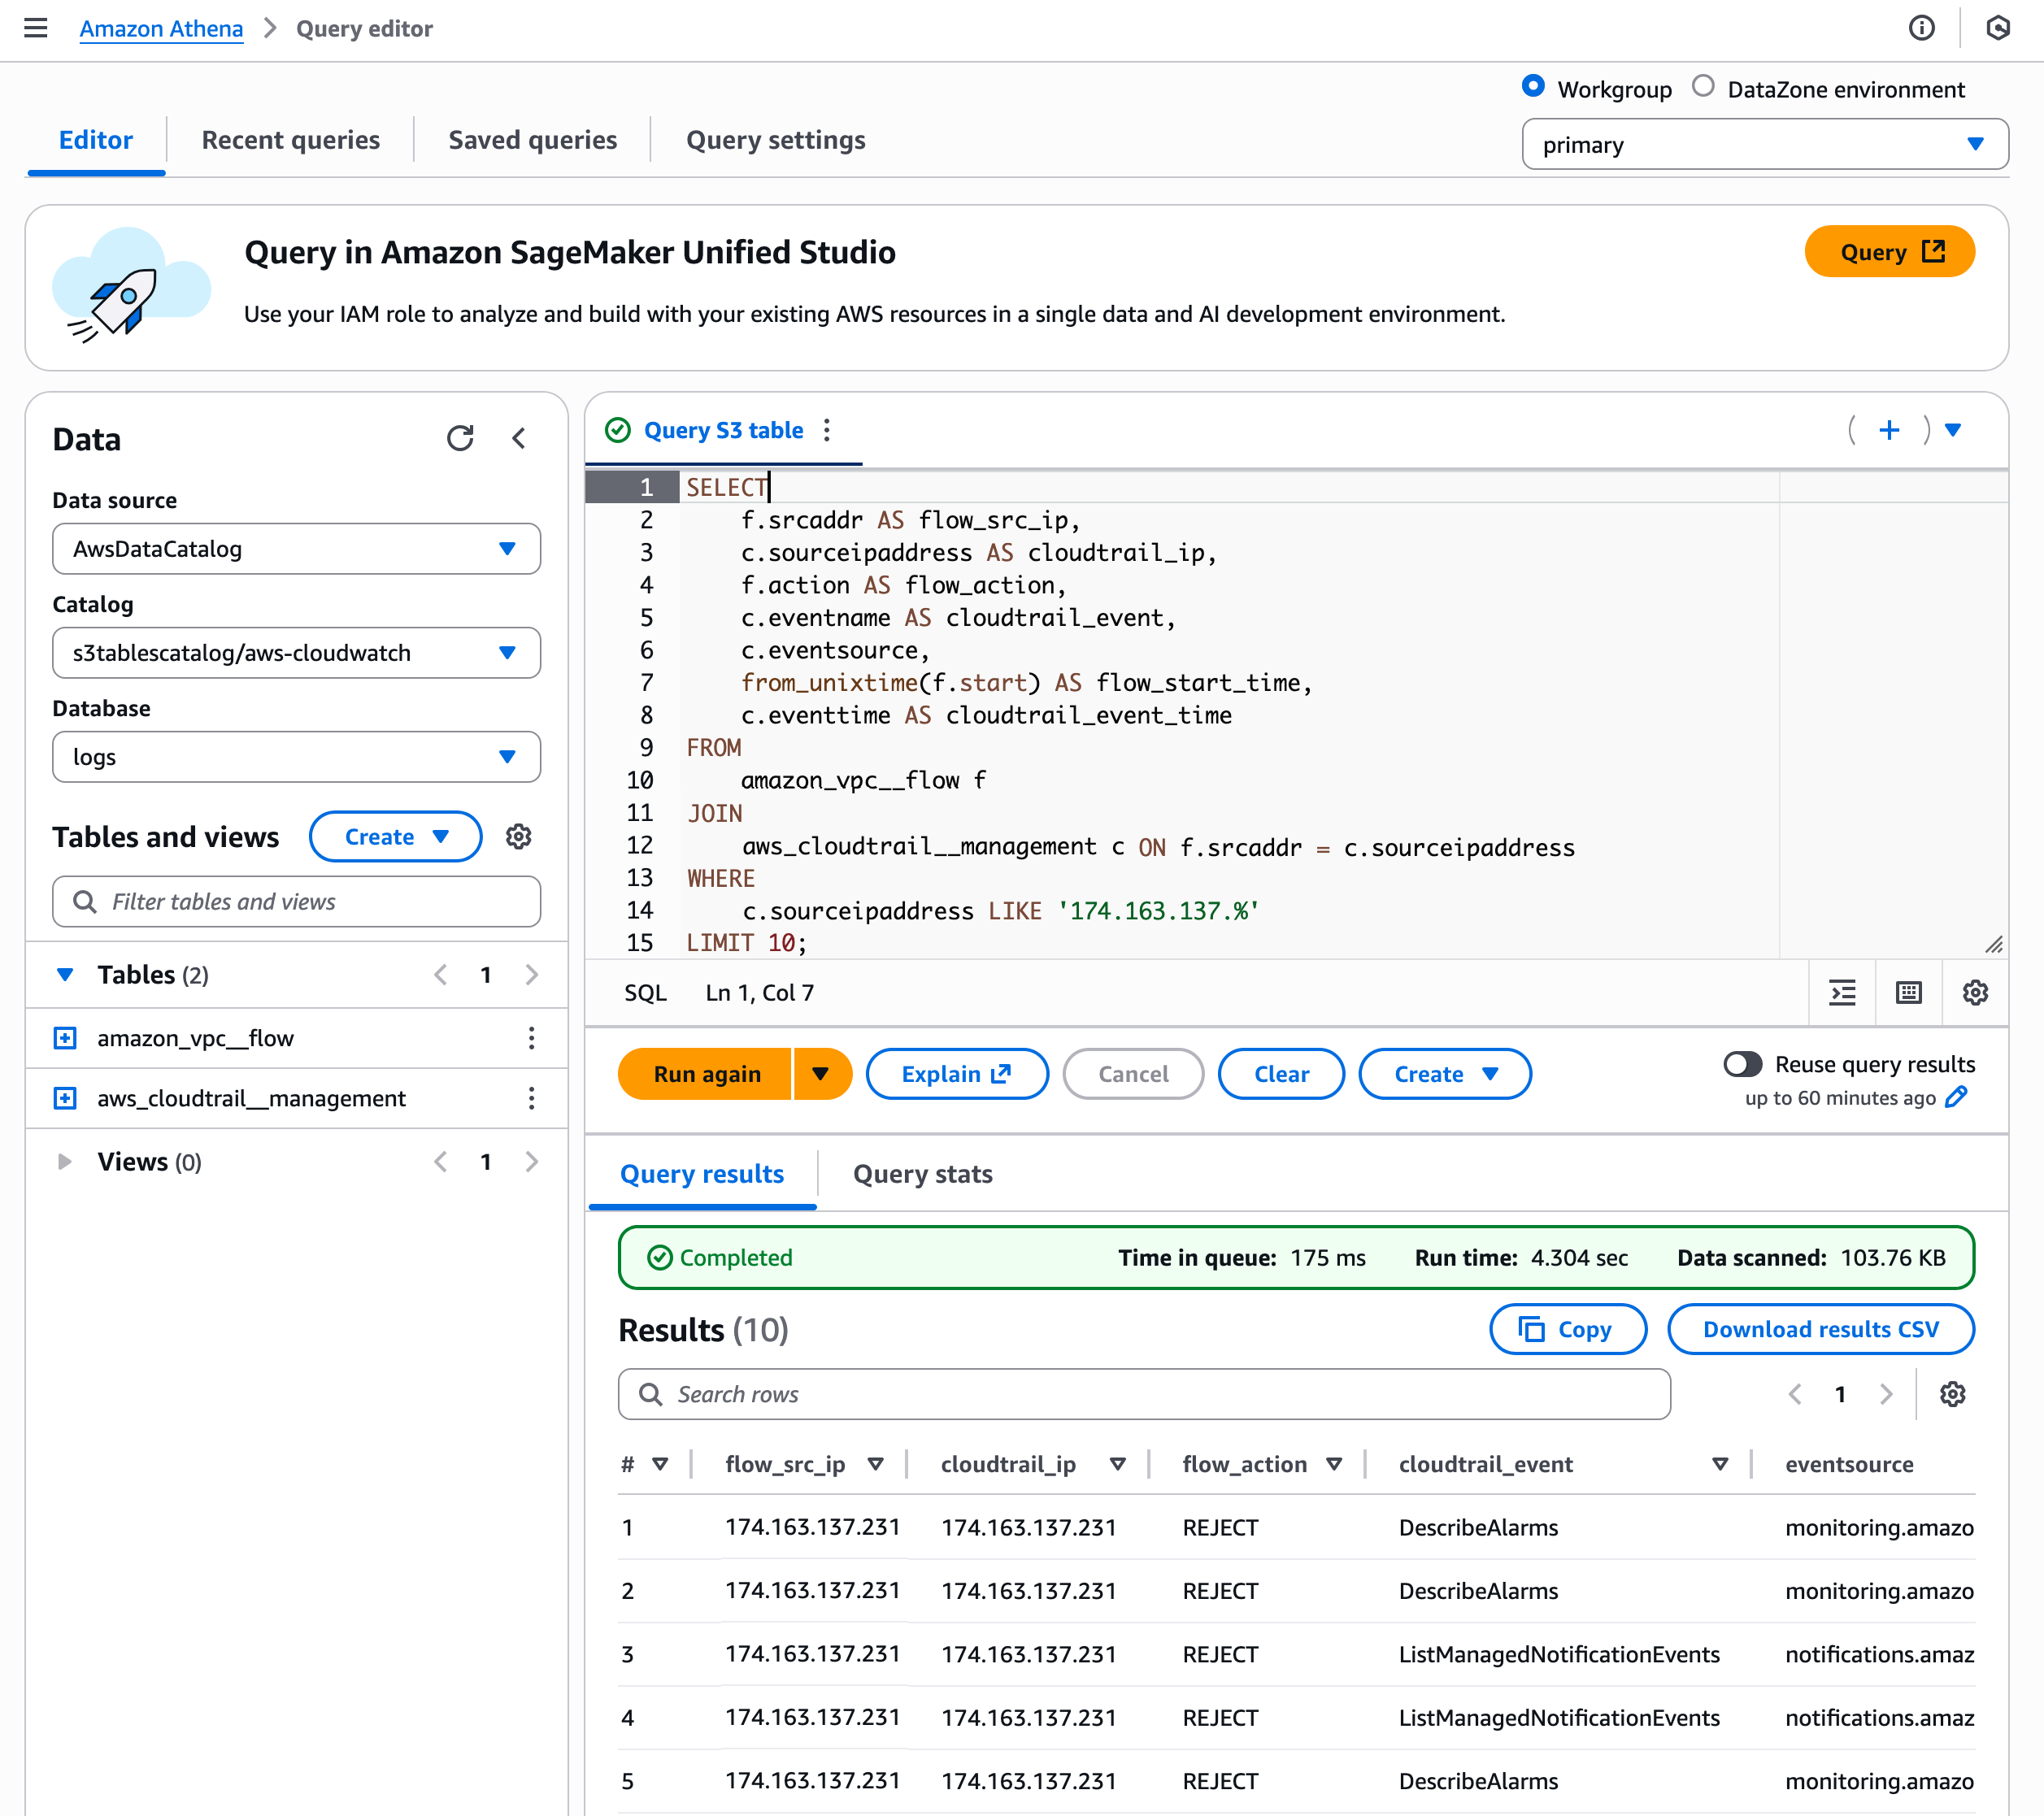
As I previously noted, you can integrate data sources into S3 Tables and query together. For example, using a Query Editor in Athena, you can query correlates network traffic with AWS API activity from a specific IP range (174.163.137.*) by joining VPC Flow Logs with CloudTrail logs based on matching source IP addresses.

This type of integrated search is particularly valuable for security monitoring, incident investigation, and suspicious behavior detection. You can view if an IP that’s making network connections is also performing sensitive AWS operations such as creating users, modifying security groups, or accessing data.

To learn more, visit S3 Tables integration with CloudWatch in the CloudWatch Logs User Guide.

Now available
New log management features of Amazon CloudWatch are available today in all AWS Regions except the AWS GovCloud (US) Regions and China Regions. For Regional availability and future roadmap, visit the AWS Capabilities by Region. There are no upfront commitments or minimum fees, and you pay for the usage of existing CloudWatch Logs for data ingestion, storage, and queries. To learn more, visit the CloudWatch pricing page.

Give it a try in the CloudWatch console. To learn more, visit the CloudWatch product page and send feedback to AWS re:Post for CloudWatch Logs or through your usual AWS Support contacts.

Channy

Introducing Amazon EC2 X8aedz instances powered by 5th Gen AMD EPYC processors for memory-intensive workloads

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-amazon-ec2-x8aedz-instances-powered-by-5th-gen-amd-epyc-processors-for-memory-intensive-workloads/

Today, we’re announcing the availability of new memory-optimized, high-frequency Amazon Elastic Compute Cloud (Amazon EC2) X8aedz instances powered by a 5th Gen AMD EPYC processor. These instances offer the highest CPU frequency, 5GHz in the cloud. They deliver up to two times higher compute performance and 31% price-performance compared to previous generation X2iezn instances.

X8aedz instances are ideal for electronic design automation (EDA) workloads, such as physical layout and physical verification jobs, and relational databases that benefit from high single-threaded processor performance and a large memory footprint. The combination of 5 GHz processors and local NVMe storage enables faster processing of memory-intensive backend EDA workloads such as floor planning, logic placement, clock tree synthesis (CTS), routing, and power/signal integrity analysis. The high memory-to-vCPU ratio of 32:1 makes these instances particularly effective for applications with vCPU-based licensing models.

Let me explain the instance type naming: The “a” suffix indicates an AMD processor, “e” denotes extended memory in the memory-optimized instance family, “d” represents local NVMe-based SSDs physically connected to the host server, and “z” indicates high-frequency processors.

X8aedz instances
X8aedz instances are available in eight sizes ranging from 2–96 vCPUs with 64–3,072 GiB of memory, including two bare metal sizes. X8aedz instances feature up to 75 Gbps of network bandwidth with support for the Elastic Fabric Adapter (EFA), up to 60 Gbps of throughput to the Amazon Elastic Block Store (Amazon EBS), and up to 8 TB of local NVMe SSD storage.

Here are the specs for X8aedz instances:

Instance name vCPUs Memory
(GiB)
NVMe SSD storage (GB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
x8aedz.large 2 64 158 Up to 18.75 Up to 15
x8aedz.xlarge 4 128 316 Up to 18.75 Up to 15
x8aedz.3xlarge 12 384 950 Up to 18.75 Up to 15
x8aedz.6xlarge 24 768 1,900 18.75 15
x8aedz.12xlarge 48 1,536 3,800 37.5 30
x8aedz.24xlarge 96 3,072 7,600 75 60
x8aedz.metal-12xl 48 1,536 3,800 37.5 30
x8aedz.metal-24xl 96 3,072 7,600 75 60

With the 60 Gbps Amazon EBS bandwidth and up to 8 TB of local NVMe SSD storage, you can achieve faster database response times and reduced latency for EDA operations, ultimately accelerating time-to-market for chip designs. These instances also support the instance bandwidth configuration feature that offers flexibility in allocating resources between network and EBS bandwidth. You can scale network or EBS bandwidth by 25% and improve database (read and write) performance, query processing, and logging speeds.

X8aedz instances use sixth-generation AWS Nitro cards, which offload CPU virtualization, storage, and networking functions to dedicated hardware and software, enhancing performance and security for your workloads.

Now available
Amazon EC2 X8aedz instances are now available in US West (Oregon) and Asia Pacific (Tokyo) AWS Regions, and additional Regions will be coming soon. For Regional availability and future roadmap, search the instance type in the AWS CloudFormation resources tab of the AWS Capabilities by Region.

You can purchase these instances as On-Demand, Savings Plan, Spot Instances, and Dedicated Instances. To learn more, visit the Amazon EC2 Pricing page.

Give X8aedz instances a try in the Amazon EC2 console. To learn more, visit the Amazon EC2 X8aedz instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

Channy

AWS Transform for mainframe introduces Reimagine capabilities and automated testing functionality

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-transform-for-mainframe-introduces-reimagine-capabilities-and-automated-testing-functionality/

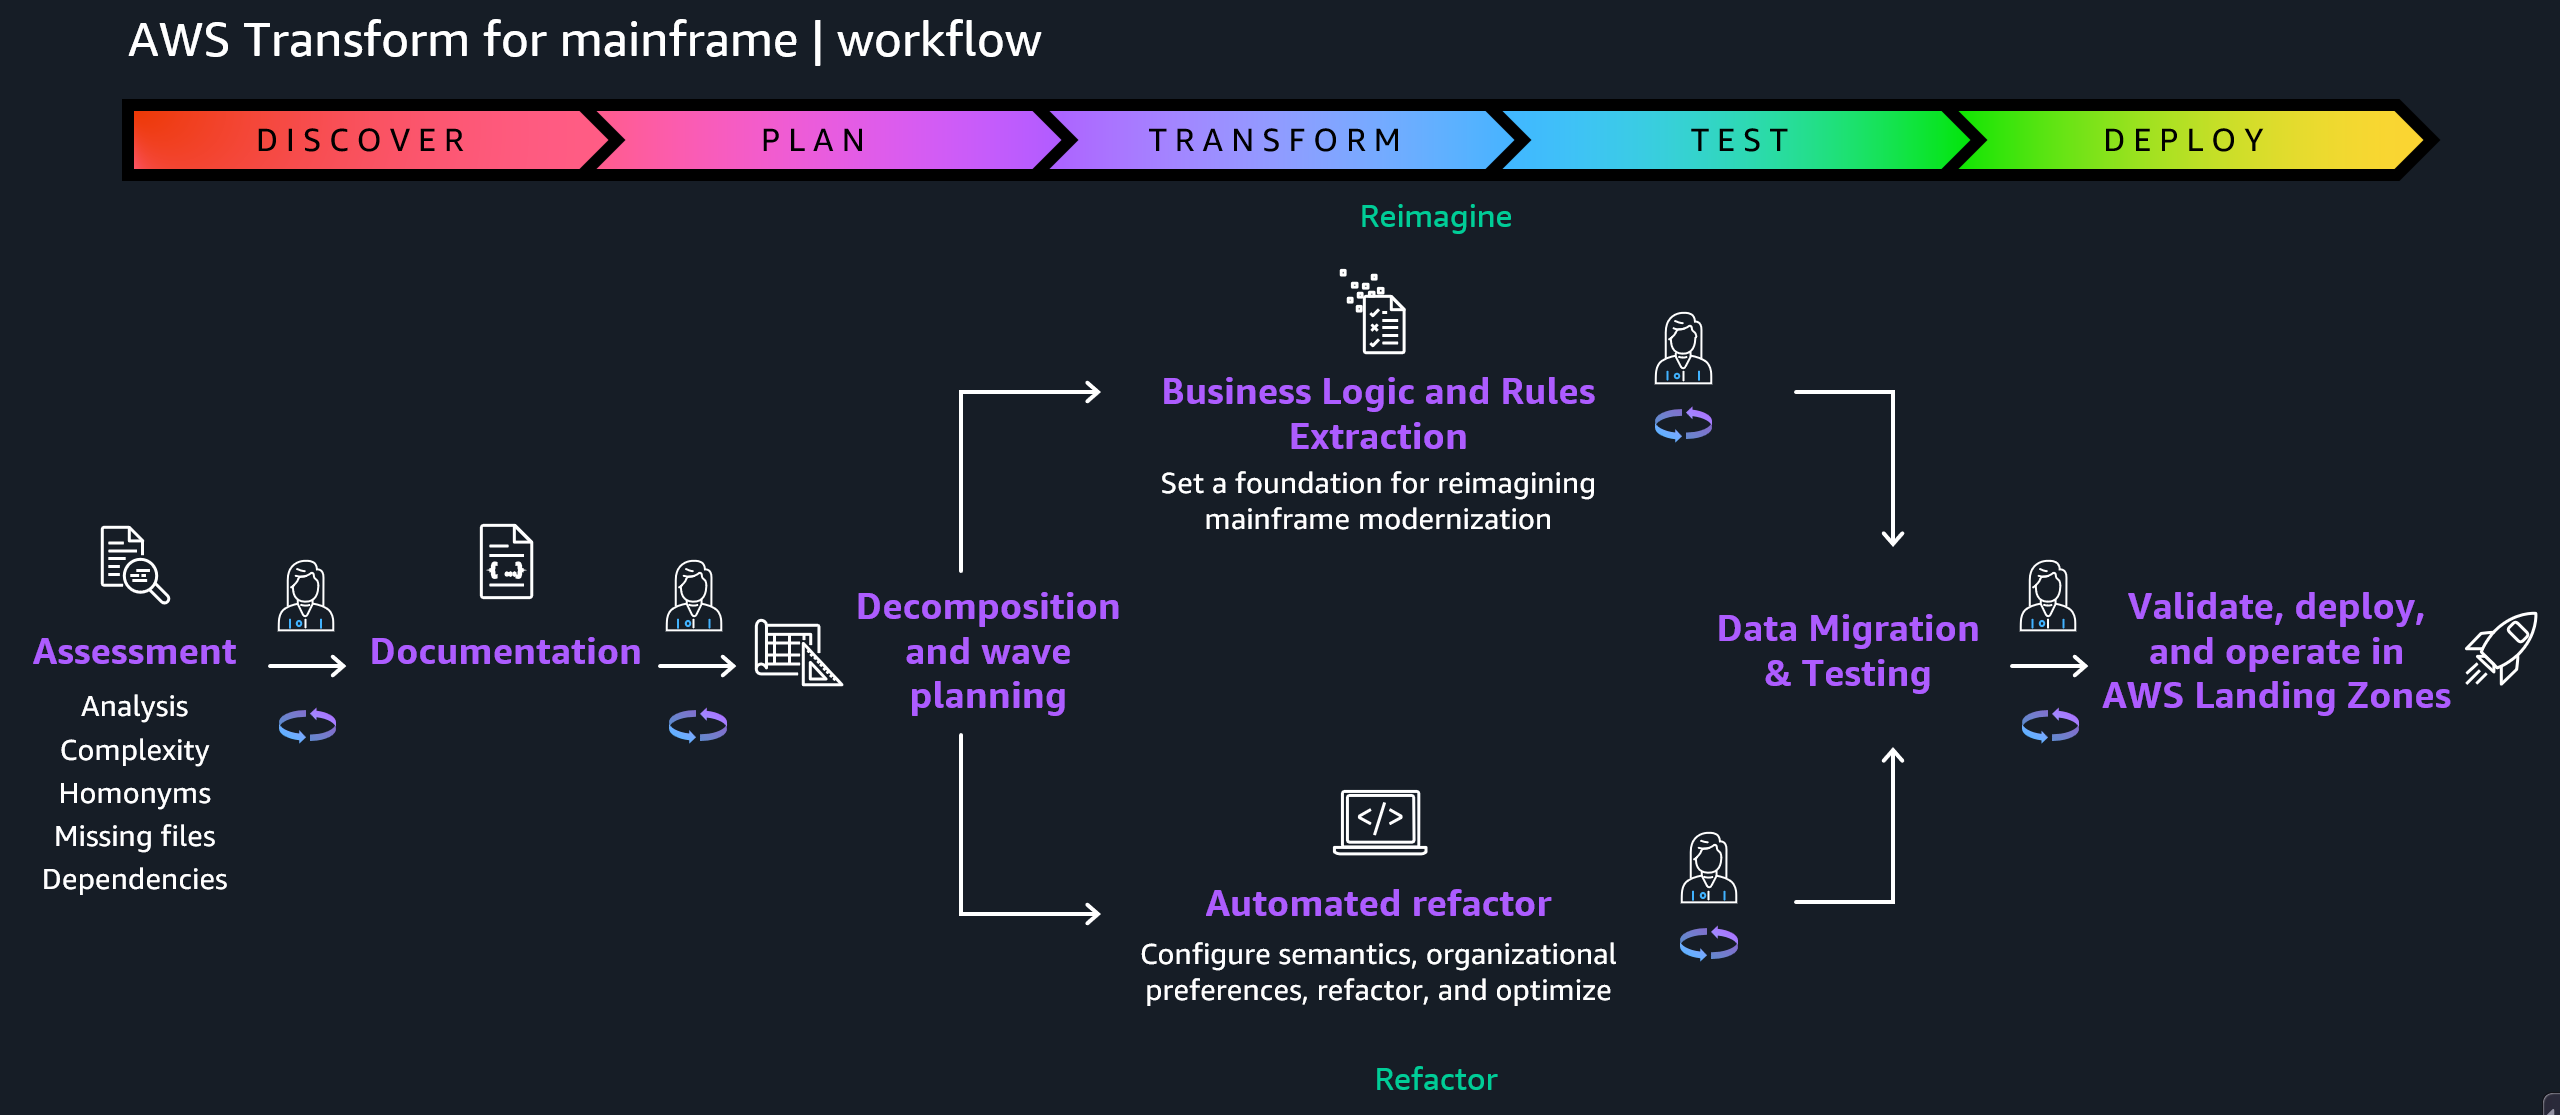
In May, 2025, we launched AWS Transform for mainframe, the first agentic AI service for modernizing mainframe workloads at scale. The AI-powered mainframe agent accelerates mainframe modernization by automating complex, resource-intensive tasks across every phase of modernization—from initial assessment to final deployment. You can streamline the migration of legacy mainframe applications, including COBOL, CICS, DB2, and VSAM to modern cloud environments—cutting modernization timelines from years to months.

Today, we’re announcing enhanced capabilities in AWS Transform for mainframe that include AI-powered analysis features, support for the Reimagine modernization pattern, and testing automation. These enhancements solve two critical challenges in mainframe modernization: the need to completely transform applications rather than merely move them to the cloud, and the extensive time and expertise required for testing.

  • Reimagining mainframe modernization – This is a new AI-driven approach that completely reimagines the customer’s application architecture using modern patterns or moving from batch process to real-time functions. By combining the enhanced business logic extraction with new data lineage analysis and automated data dictionary generation from the legacy source code through AWS Transform, customers transform monolithic mainframe applications written in languages like COBOL into more modern architectural styles, like microservices.
  • Automated testing – Customers can use new automated test plan generation, test data collection scripts, and test case automation scripts. AWS Transform for mainframe also provides functional testing tools for data migration, results validation, and terminal connectivity. These AI-powered capabilities work together to accelerate testing timelines and improve accuracy through automation.

Let’s learn more about reimagining mainframe modernization and automated testing capabilities.

How to reimagine mainframe modernization
We recognize that mainframe modernization is not a one-size-fits-all proposition. Whereas tactical approaches focus on augmentation and maintaining existing systems, strategic modernization offers distinct paths: Replatform, Refactor, Replace, or the new Reimagine.

In the Reimagine pattern, AWS Transform AI-powered analysis combines mainframe system analysis with organizational knowledge to create detailed business and technical documentation and architecture recommendations. This helps preserve critical business logic while enabling modern cloud-native capabilities.

AWS Transform provides new advanced data analysis capabilities that are essential for successful mainframe modernization, including data lineage analysis and automated data dictionary generation. These features work together to define the structure and meaning to accompany the usage and relationships of mainframe data. Customers gain complete visibility into their data landscape, enabling informed decision-making for modernization. Their technical teams can confidently redesign data architectures while preserving critical business logic and relationships.

The Reimagining strategy follows the principle of human in the loop validation, which means that AI-generated application specifications and code such as AWS Transform and Kiro are continuously validated by domain experts. This collaborative approach between AI capabilities and human judgment significantly reduces transformation risk while maintaining the speed advantages of AI-powered modernization.

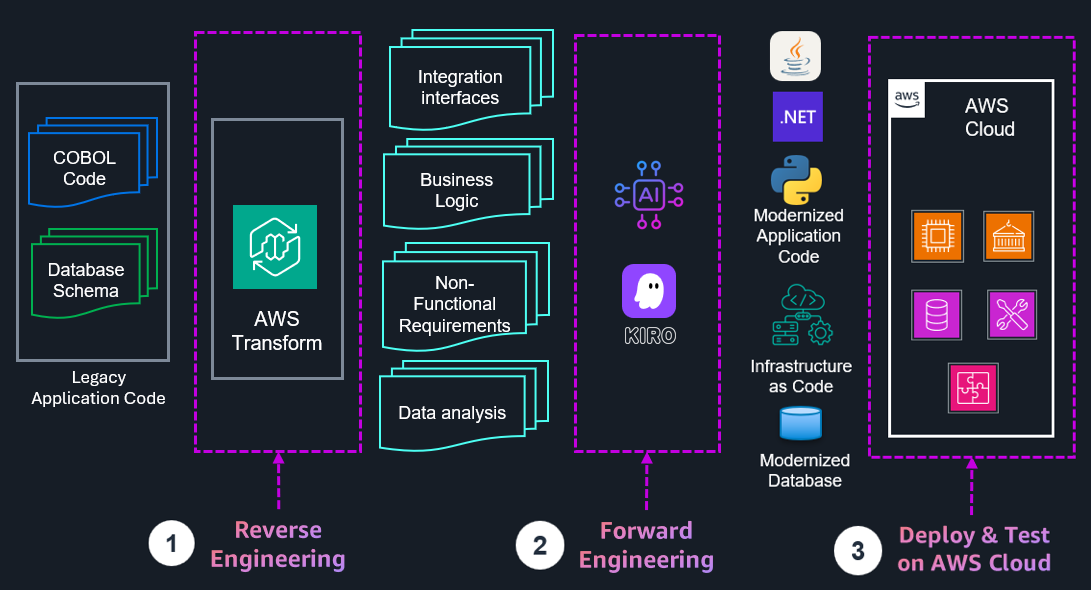
The pathway has a three-phase methodology to transform legacy mainframe applications into cloud-native microservices:

  • Reverse engineering to extract business logic and rules from existing COBOL or job control language (JCL) code using AWS Transform for mainframe.
  • Forward engineering to generate microservice specification, modernized source code, infrastructure as code (IaC), and modernized database.
  • Deploy and test to deploy the generated microservices to Amazon Web Services (AWS) using IaC and to test the functionality of the modernized application.

Although microservices architecture offers significant benefits for mainframe modernization, it’s crucial to understand that it’s not the best solution for every scenario. The choice of architectural patterns should be driven by the specific requirements and constraints of the system. The key is to select an architecture that aligns with both current needs and future aspirations, recognizing that architectural decisions can evolve over time as organizations mature their cloud-native capabilities.

The flexible approach supports both do-it-yourself and partner-led development, so you can use your preferred tools while maintaining the integrity of your business processes. You get the benefits of modern cloud architecture while preserving decades of business logic and reducing project risk.

Automated testing in action
The new automated testing feature supports IBM z/OS mainframe batch application stack at launch, which helps organizations address a wider range of modernization scenarios while maintaining consistent processes and tooling.

Here are the new mainframe capabilities:

  • Plan test cases – Create test plans from mainframe code, business logic, and scheduler plans.
  • Generate test data collection scripts – Create JCL scripts for data collection from your mainframe to your test plan.
  • Generate test automation scripts – Generate execution scripts to automate testing of modernized applications running in the target AWS environment.

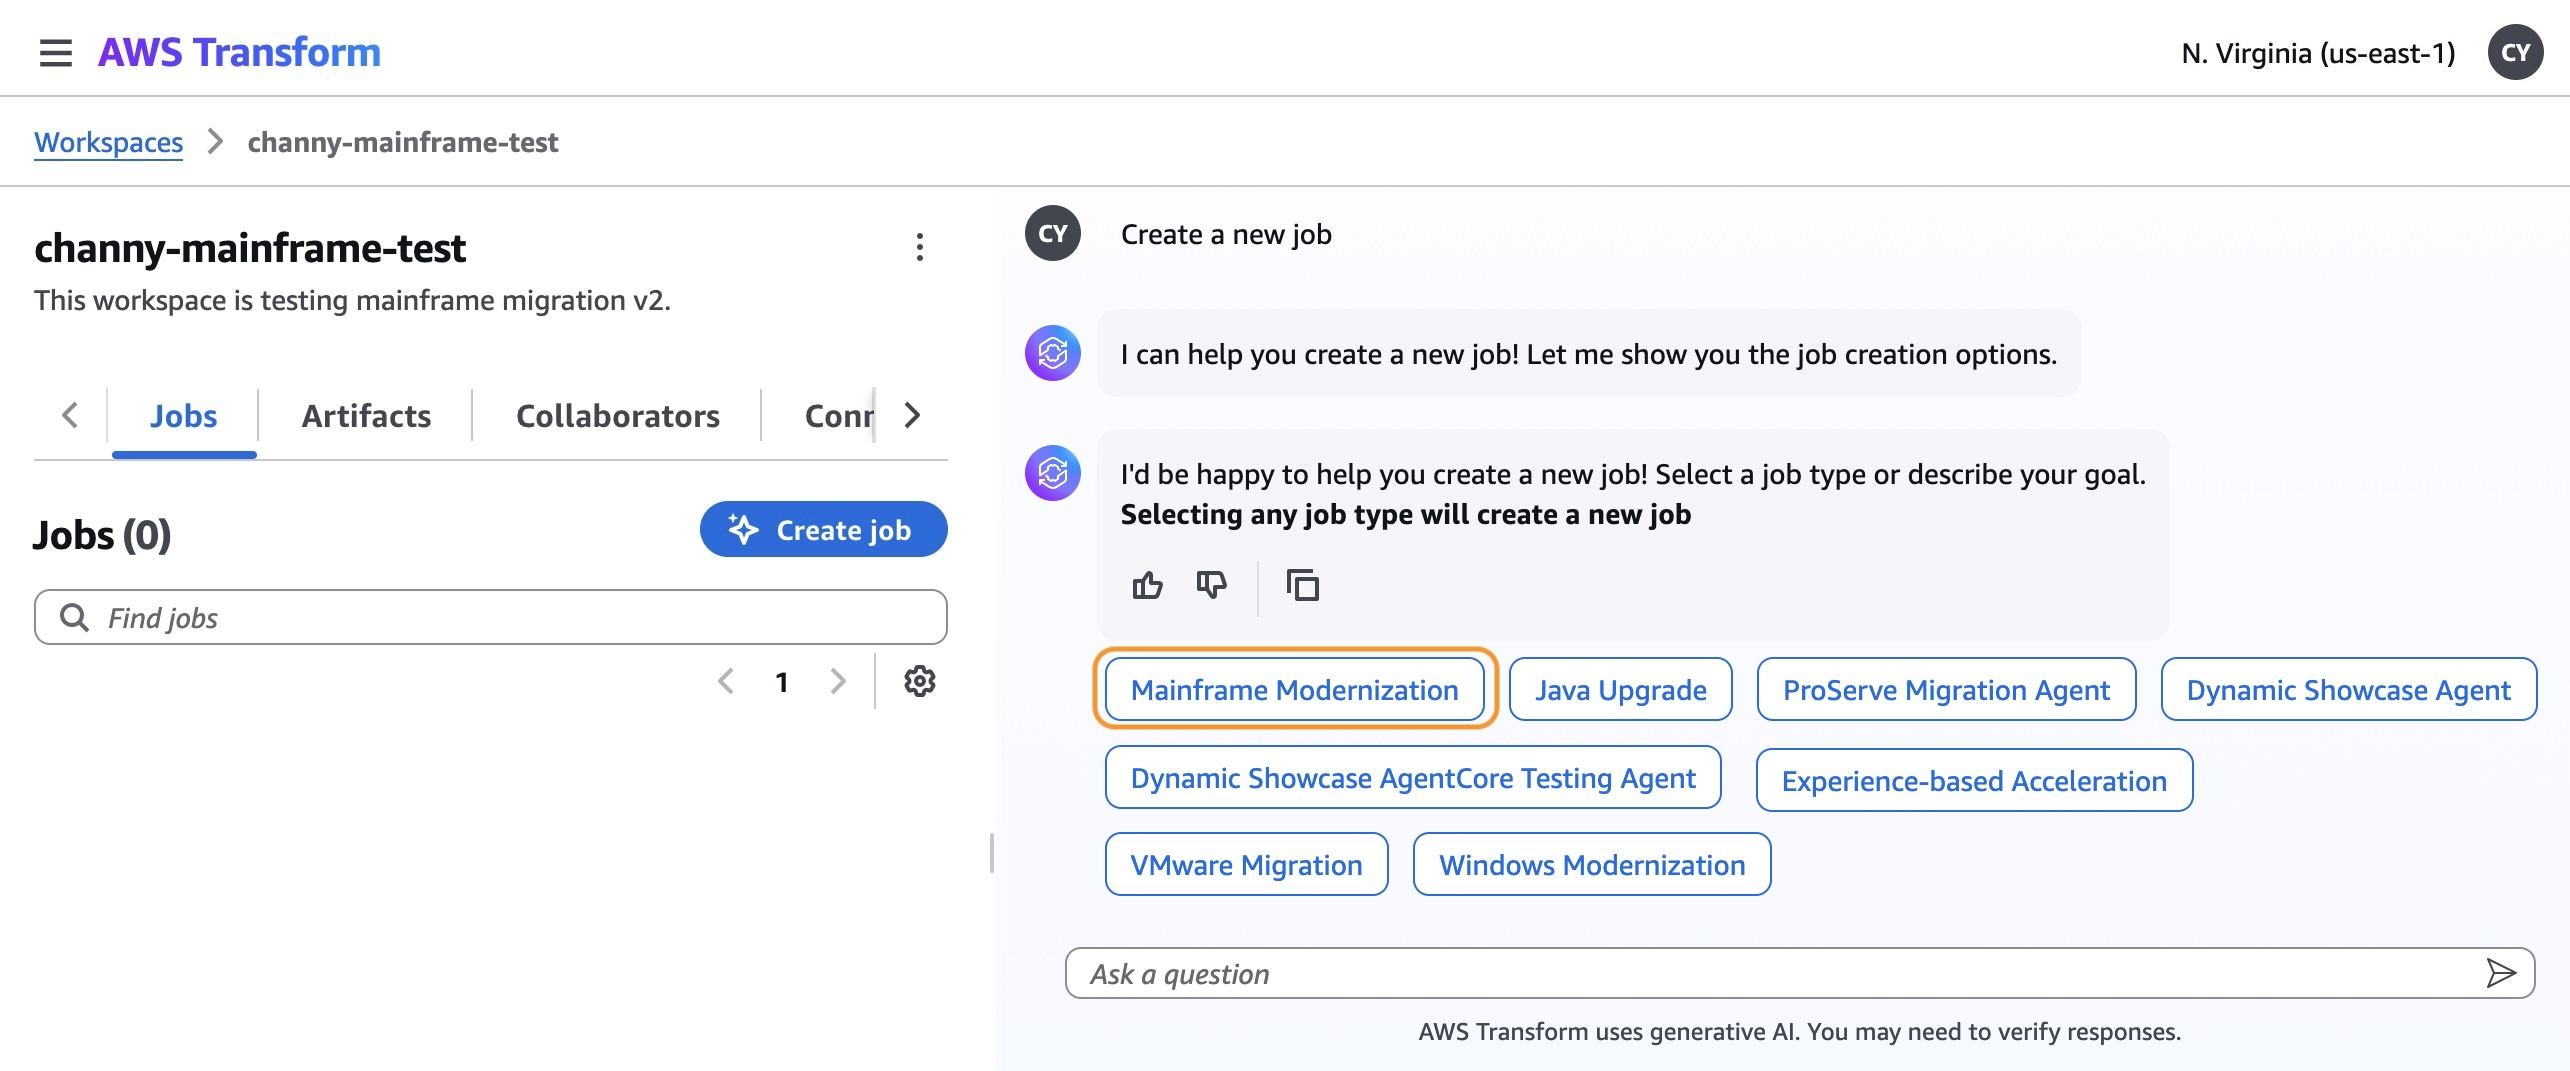
To get started with automated testing, you should set up a workspace, assign a specific role to each user, and invite them to onboard your workspace. To learn more, visit Getting started with AWS Transform in the AWS Transform User Guide.

Choose Create job in your workspace. You can see all types of supported transformation jobs. For this example, I select the Mainframe Modernization job to modernize mainframe applications.

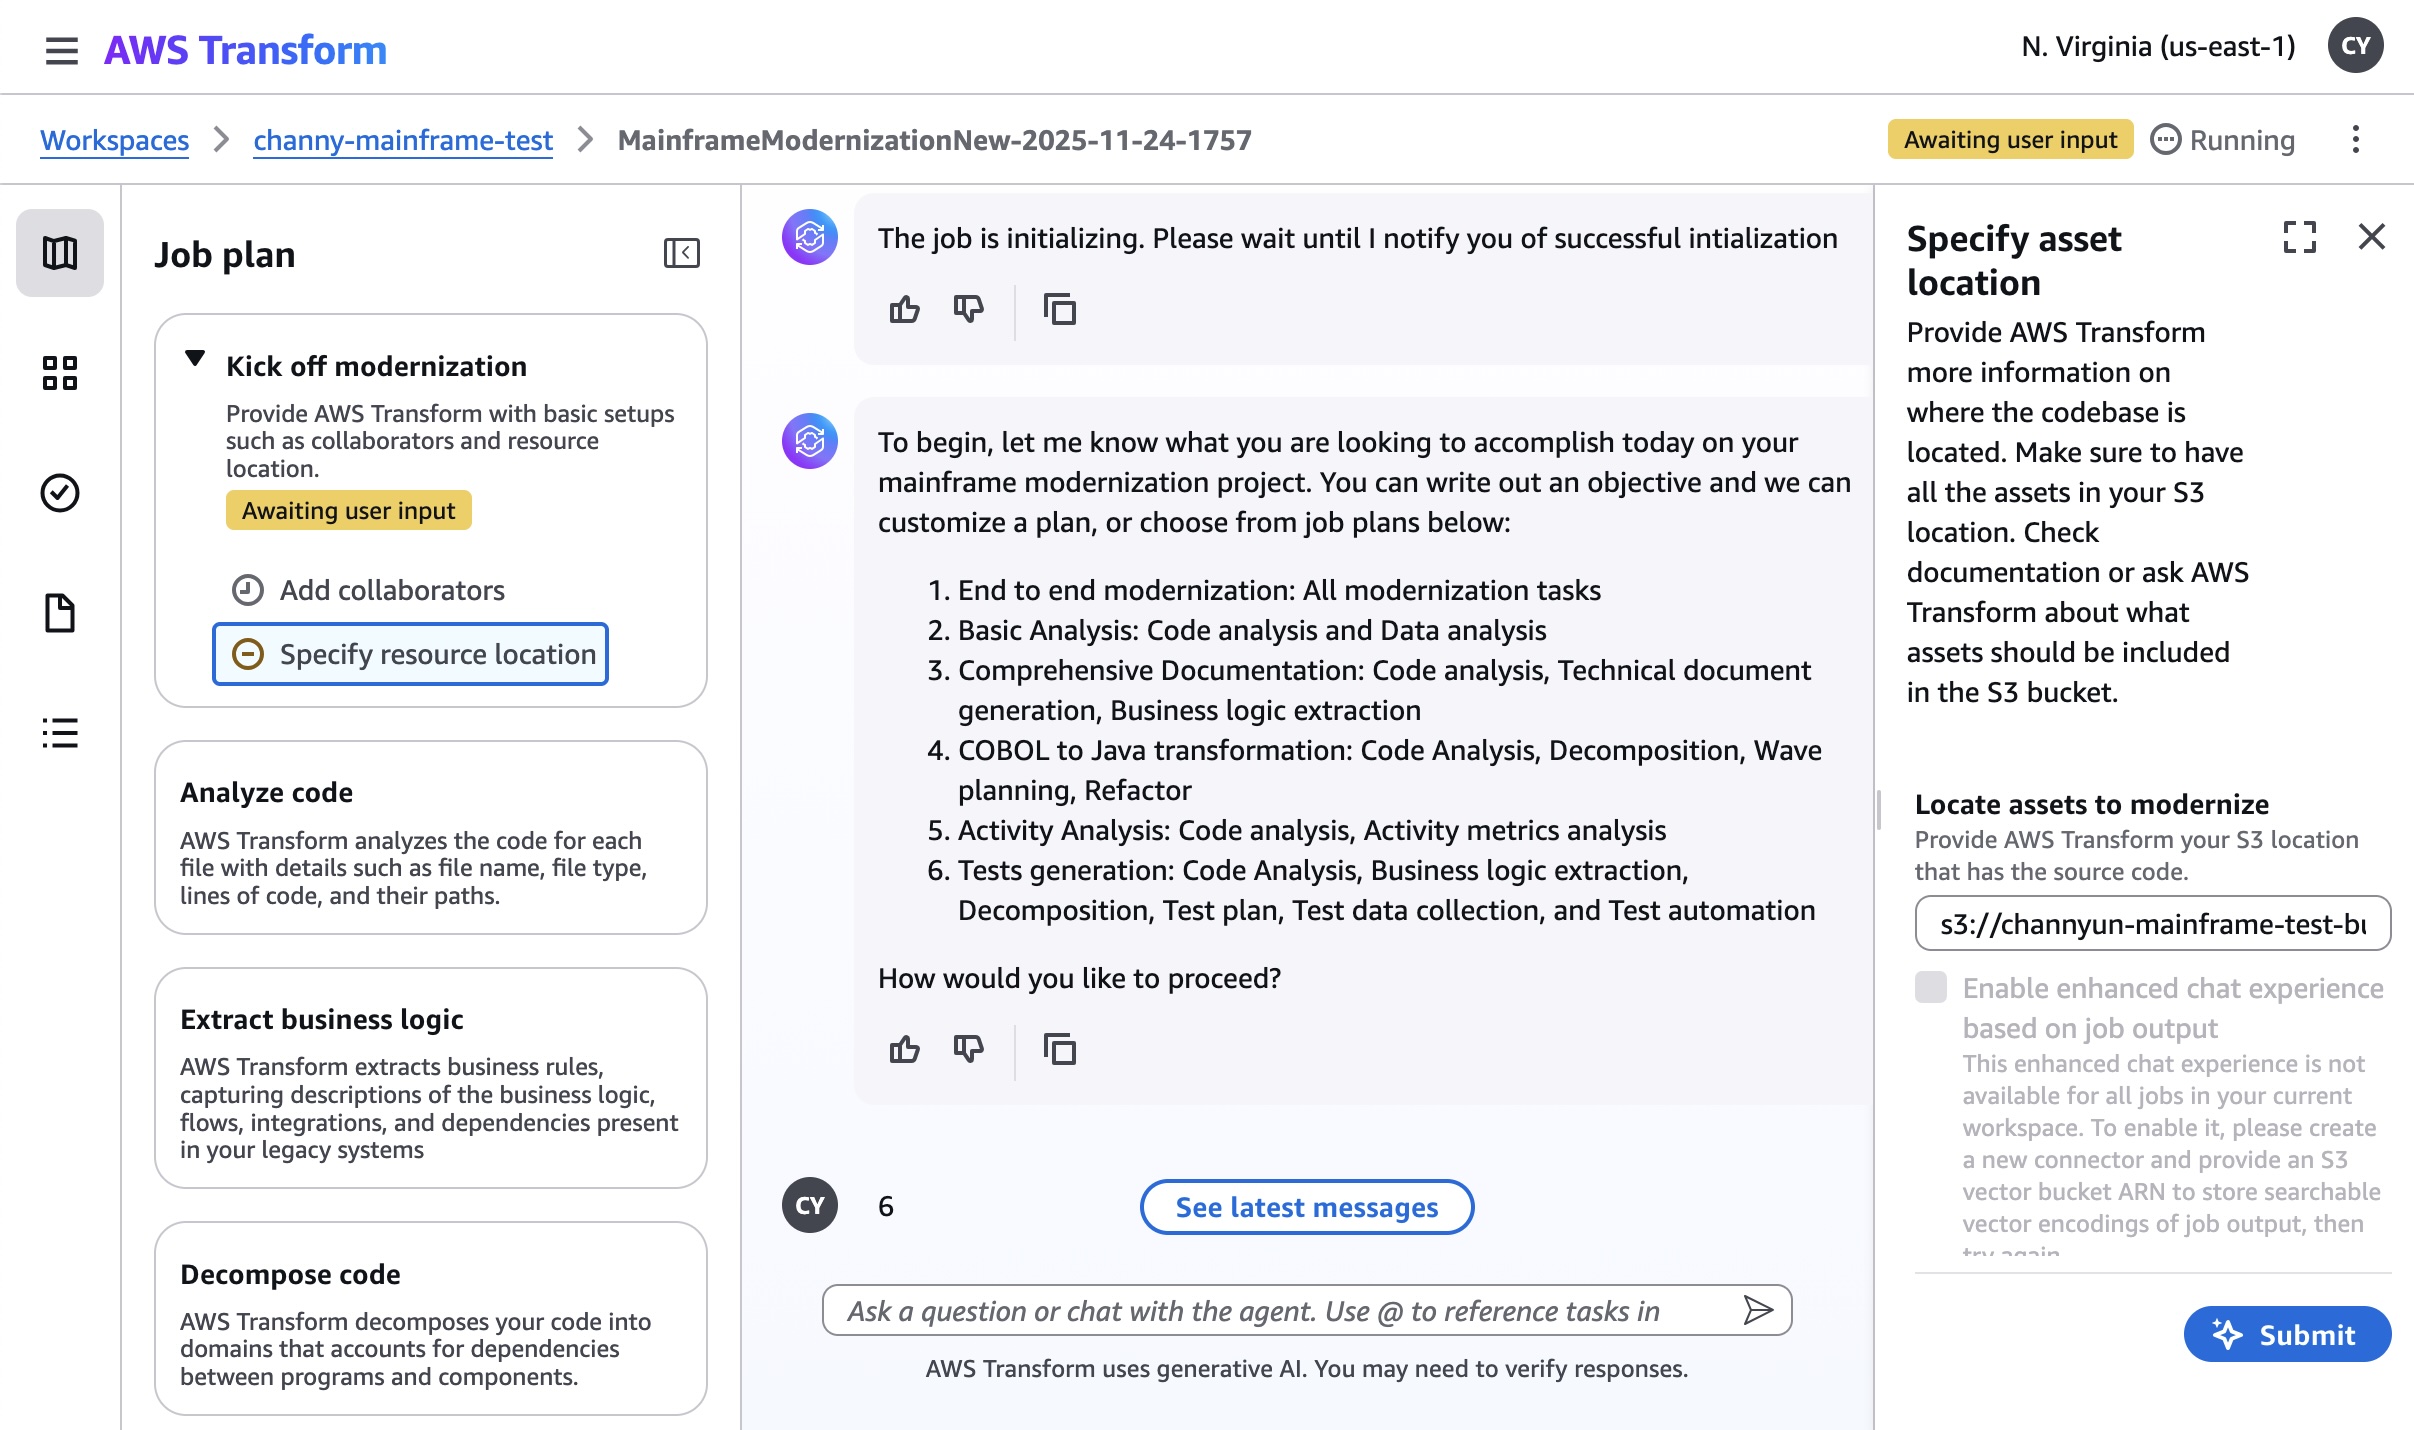
After a new job is created, you can kick off modernization for tests generation. This workflow is sequential and it is a place for you to answer the AI agent’s questions, providing the necessary input. You can add your collaborators and specify resource location where the codebase or documentation is located in your Amazon Simple Storage Service (Amazon S3) bucket.

I use a sample application for a credit card management system as the mainframe banking case with the presentation (BMS screens), business logic (COBOL) and data (VSAM/DB2), including online transaction processing and batch jobs.

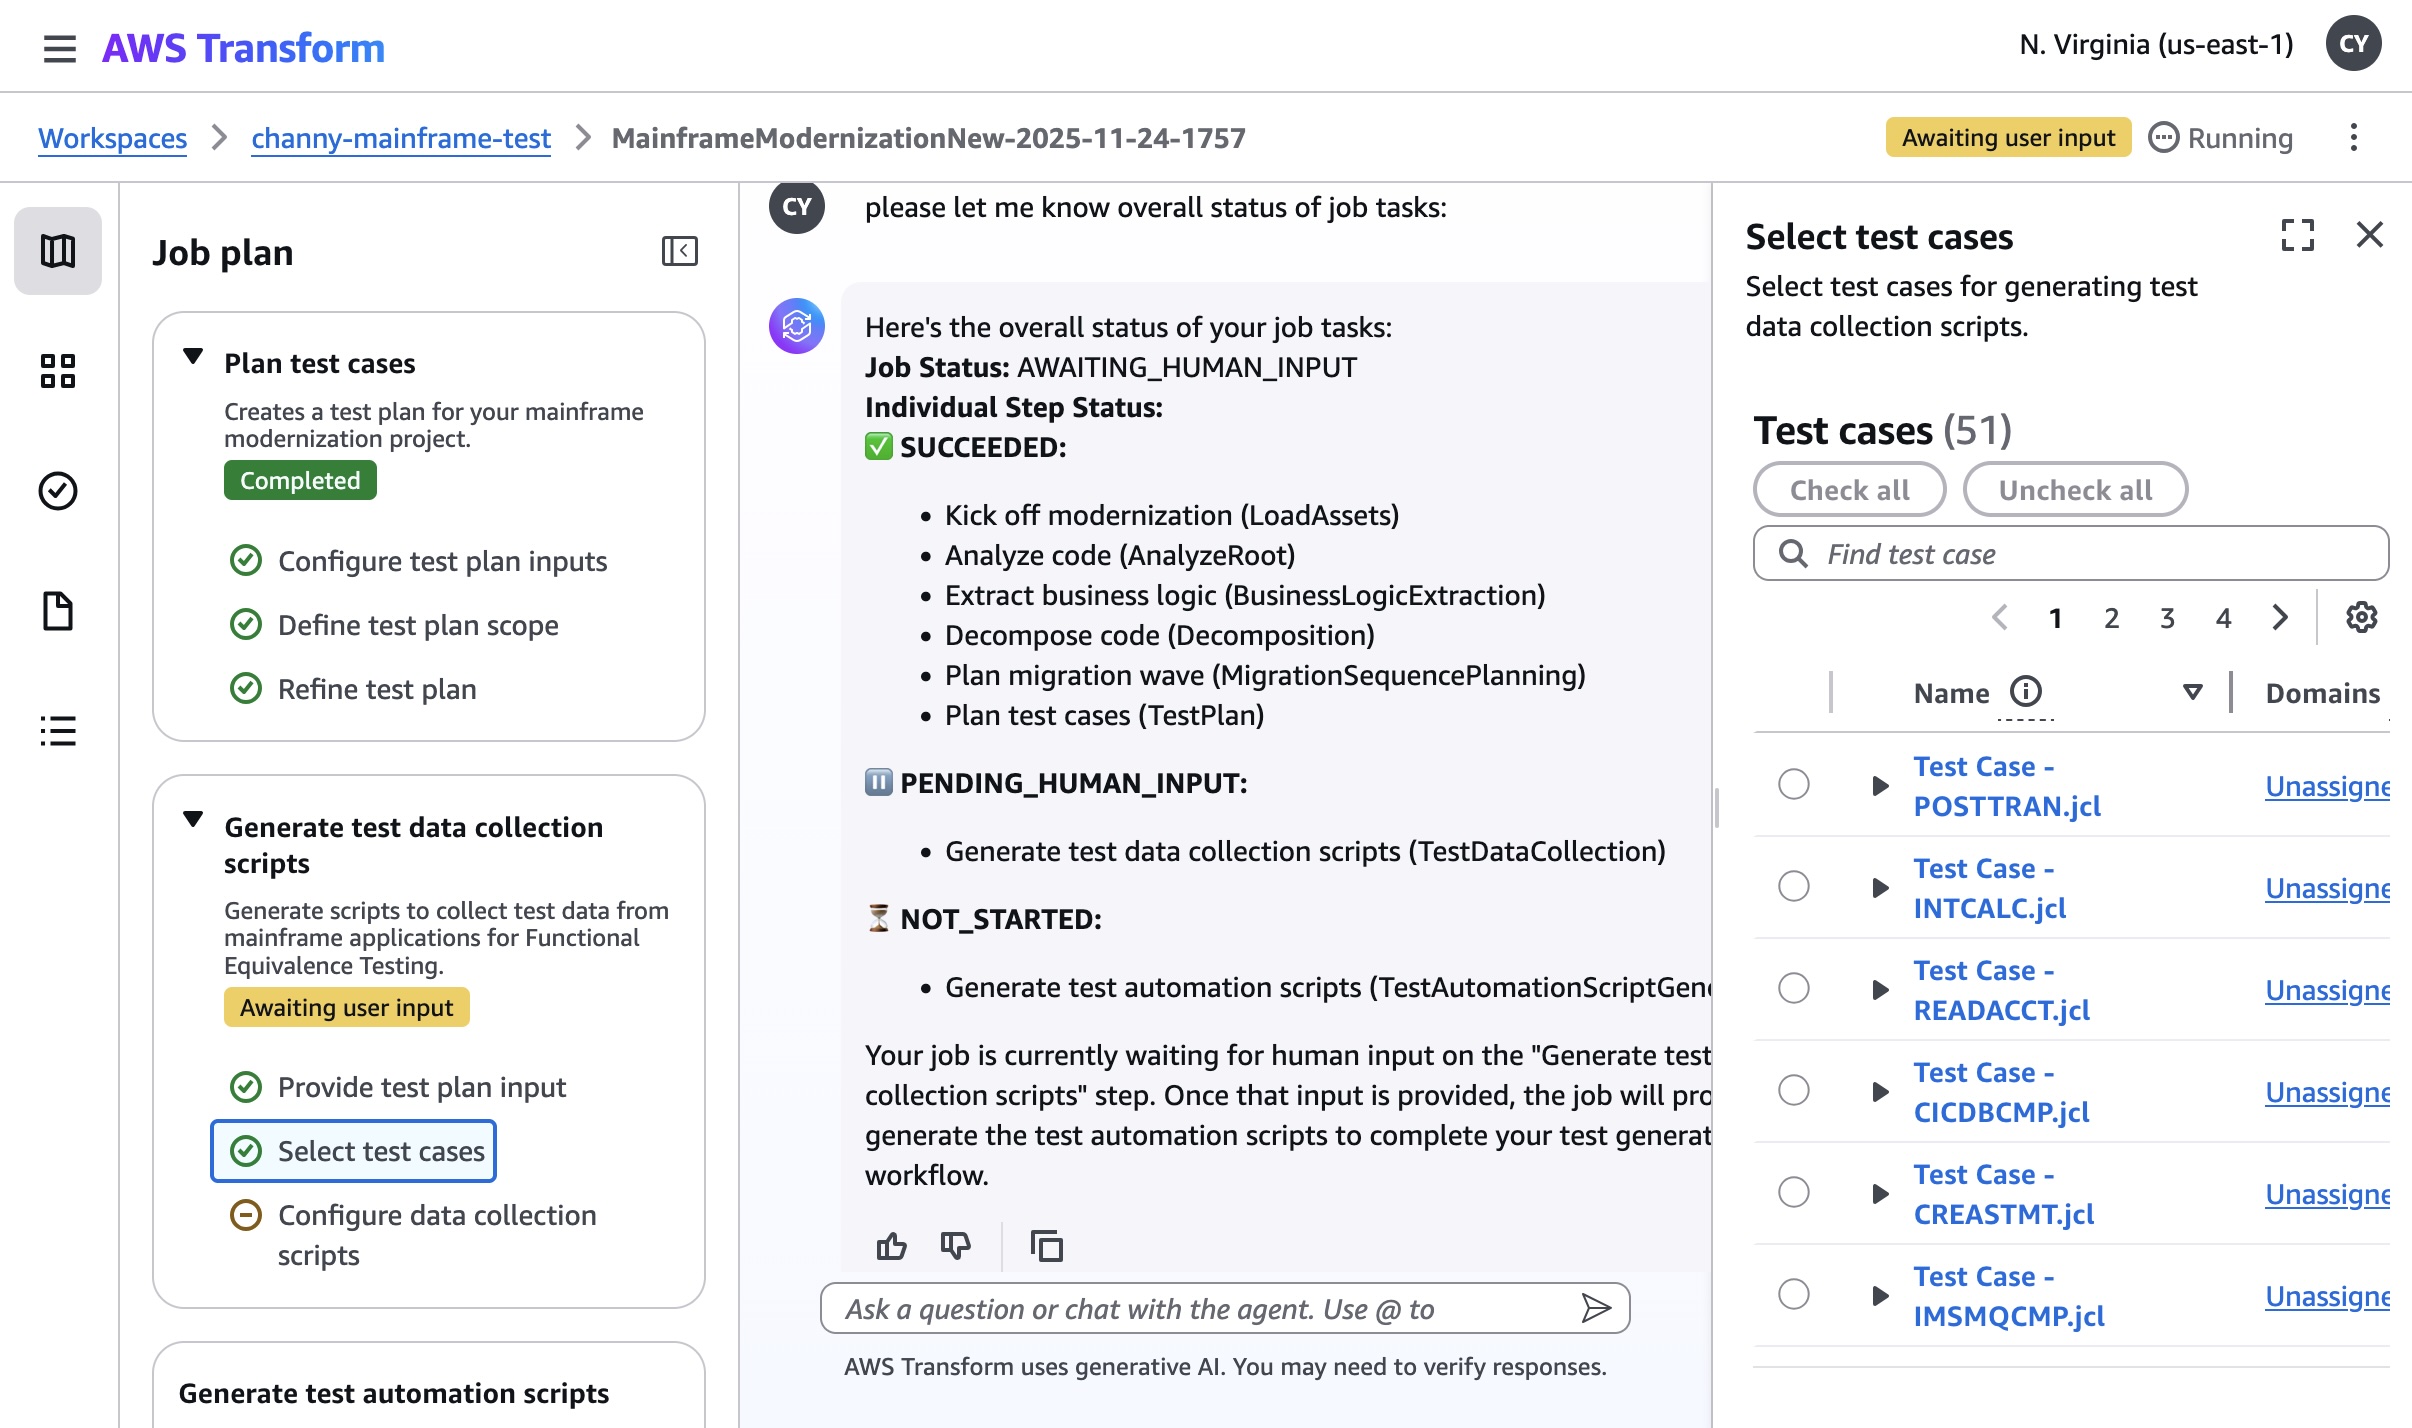
After finishing the steps of analyzing code, extracting business logic, decomposing code, planning migration wave, you can experience new automated testing capabilities such as planning test cases, generating test data collection scripts, and test automation scripts.

The new testing workflow creates a test plan for your modernization project and generates test data collection scripts. You will have three planning steps:

  • Configure test plan inputs – You can link your test plan to your other job files. The test plan is generated based on analyzing the mainframe application code and can provide more details optionally using the extracted business logic, the technical documentation, the decomposition, and using a scheduler plan.
  • Define test plan scope – You can define the entry point, the specific program where the application’s execution flow begins. For example, the JCL for a batch job. In the test plan, each functional test case is designed to start the execution from a specific entry point.
  • Refine test plan – A test plan is made up of sequential test cases. You can reorder them, add new ones, merge multiple cases, or split one into two on the test case detail page. Batch test cases are composed of a sequence of JCLs following the scheduler plan.

Generating test data collection scripts collects test data from mainframe applications for functional equivalence testing. This step actively generates JCL scripts that will help you gather test data from the sample application’s various data sources (such as VSAM files or DB2 databases) for use in testing the modernized application. The step is designed to create automated scripts that can extract test data from VSAM datasets, query DB2 tables for sample data, collect sequential data sets, and generate data collection workflows. After this step is completed, you’ll have comprehensive test data collection scripts ready to use.

To learn more about automated testing, visit Modernization of mainframe applications in the AWS Transform User Guide.

Now available
The new capabilities in AWS Transform for mainframe are available today in all AWS Regions where AWS Transform for mainframe is offered. For Regional availability and future roadmap, visit the AWS Capabilities by Region. Currently, we offer our core features—including assessment and transformation—at no cost to AWS customers. To learn more, visit AWS Transform Pricing page.

Give it a try in the AWS Transform console. To learn more, visit the AWS Transform for mainframe product page and send feedback to AWS re:Post for AWS Transform for mainframe or through your usual AWS Support contacts.

Channy

Introducing AWS Lambda Managed Instances: Serverless simplicity with EC2 flexibility

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/introducing-aws-lambda-managed-instances-serverless-simplicity-with-ec2-flexibility/

Today, we’re announcing AWS Lambda Managed Instances, a new capability you can use to run AWS Lambda functions on your Amazon Elastic Compute Cloud (Amazon EC2) compute while maintaining serverless operational simplicity. This enhancement addresses a key customer need: accessing specialized compute options and optimizing costs for steady-state workloads without sacrificing the serverless development experience you know and love.

Although Lambda eliminates infrastructure management, some workloads require specialized hardware, such as specific CPU architectures, or cost optimizations from Amazon EC2 purchasing commitments. This tension forces many teams to manage infrastructure themselves, sacrificing the serverless benefits of Lambda only to access the compute options or pricing models they need. This often leads to a significant architectural shift and greater operational responsibility.

Lambda Managed Instances
You can use Lambda Managed Instances to define how your Lambda functions run on EC2 instances. Amazon Web Services (AWS) handles setting up and managing these instances in your account. You get access to the latest generation of Amazon EC2 instances, and AWS handles all the operational complexity—instance lifecycle management, OS patching, load balancing, and auto scaling. This means you can select compute profiles optimized for your specific workload requirements, like high-bandwidth networking for data-intensive applications, without taking on the operational burden of managing Amazon EC2 infrastructure.

Each execution environment can process multiple requests rather than handling just one request at a time. This can significantly reduce compute consumption, because your code can efficiently share resources across concurrent requests instead of spinning up separate execution environments for each invocation. Lambda Managed Instances provides access to Amazon EC2 commitment-based pricing models such as Compute Savings Plans and Reserved Instances, which can provide up to a 72% discount over Amazon EC2 On-Demand pricing. This offers significant cost savings for steady-state workloads while maintaining the familiar Lambda programming model.

Let’s try it out
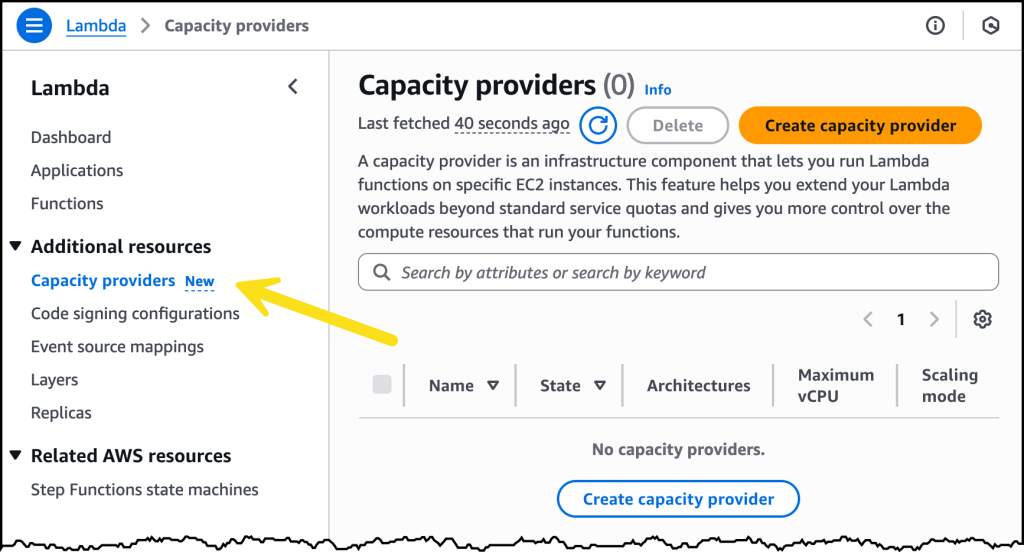
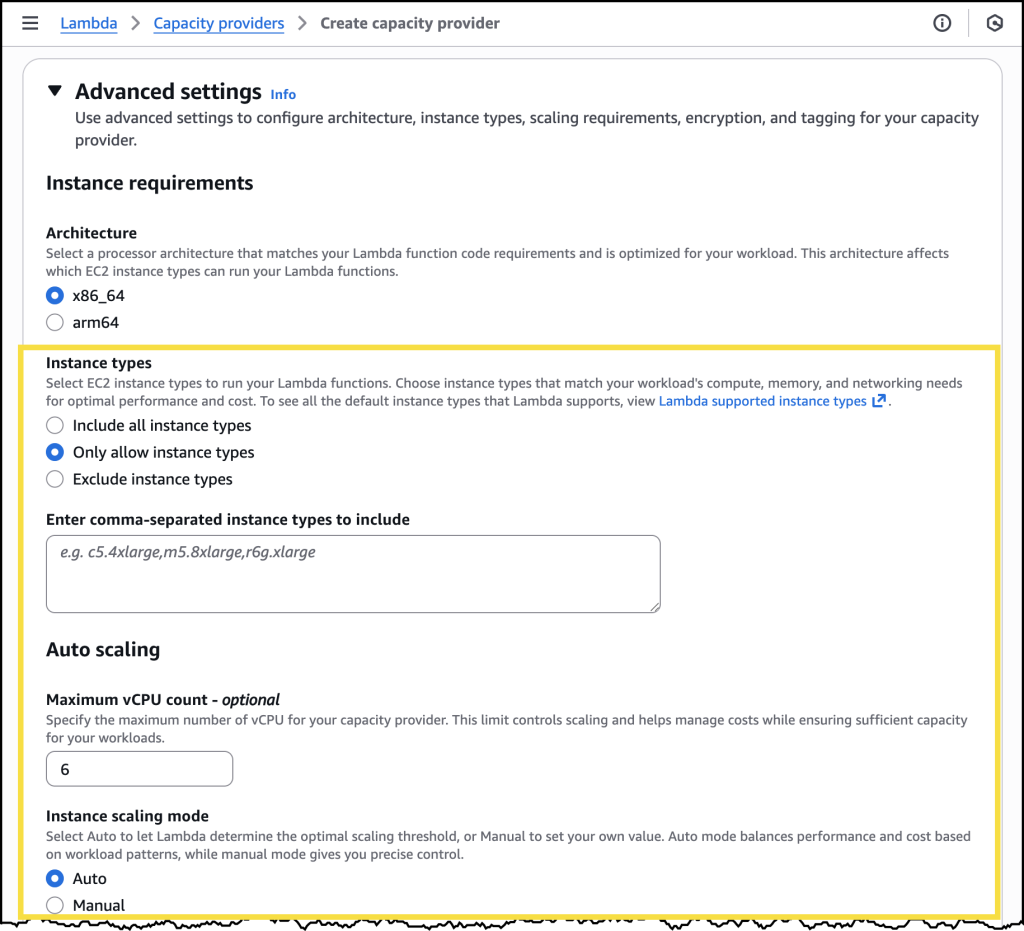
To take Lambda Managed Instances for a spin, I first need to create a Capacity provider. As shown in the following image, there is a new tab for creating these in the navigation pane under Additional resources.

Lambda Managed Instances Console

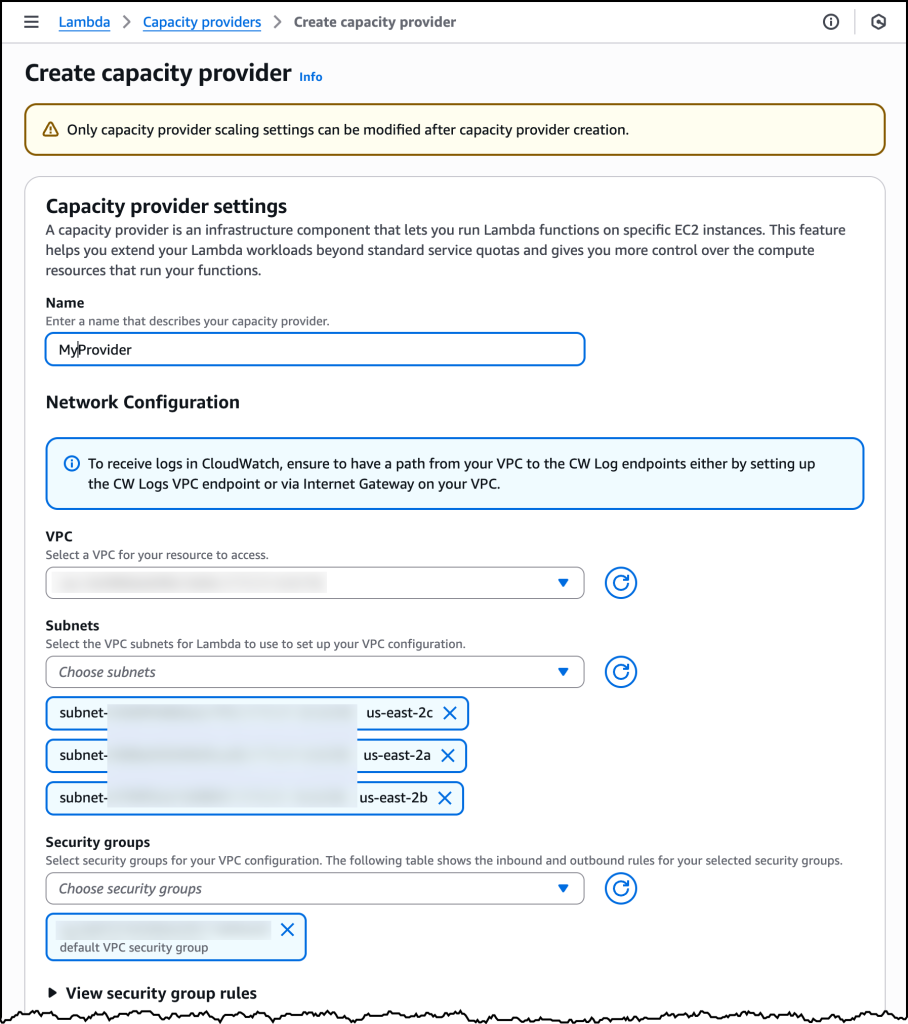
Creating a Capacity provider is where I specify the virtual private cloud (VPC), subnet configuration and security groups. With a capacity provider configuration, I can also tell Lambda where to provision and manage the instances.

I can also specify the EC2 instance types I’d like to include or exclude, or I can choose to include all instance types for high diversity. Additionally, I can specify a few controls related to auto scaling, including the Maximum vCPU count, and if I want to use Auto scaling or use a CPU policy.

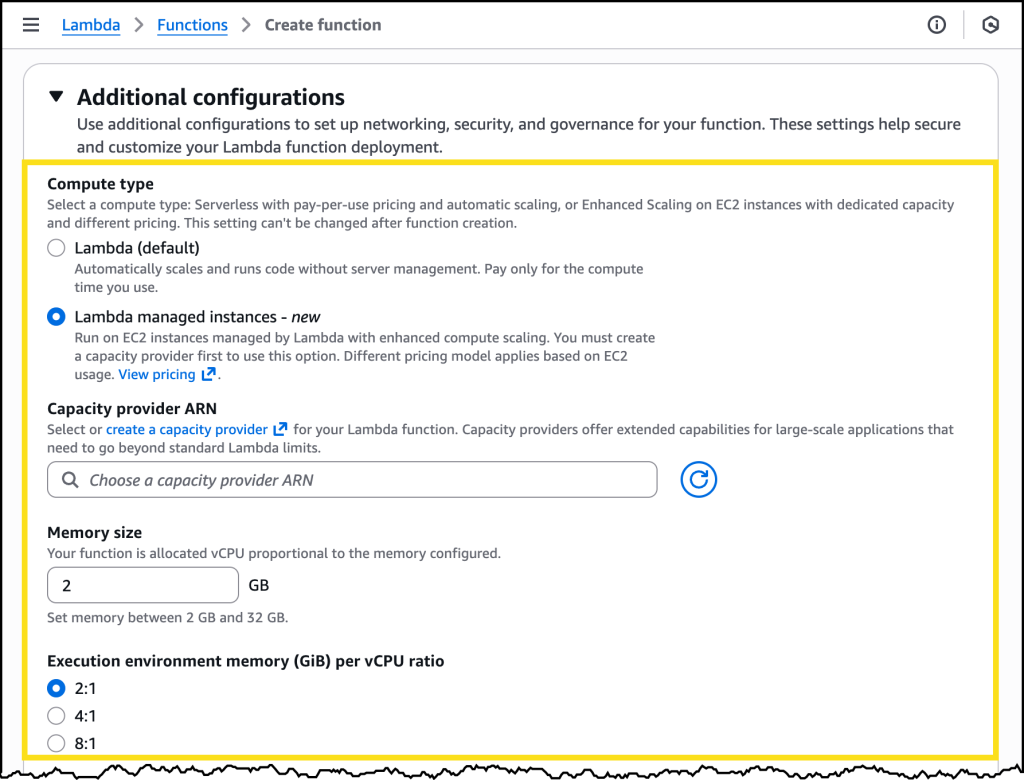
After I have my capacity provider configured, I can choose it through its Amazon Resource Name (ARN) when I go to create a new Lambda function. Here I can also select the memory allocation I want along with a memory-to-vCPU ratio.

Working with Lambda Managed Instances
Now that we’ve seen the basic setup, let’s explore how Lambda Managed Instances works in more detail. The feature organizes EC2 instances into capacity providers that you configure through the Lambda console, AWS Command Line Interface (AWS CLI), or infrastructure as code (IaC) tools such as AWS CloudFormation, AWS Serverless Application Model (AWS SAM), AWS Cloud Development Kit (AWS CDK) and Terraform. Each capacity provider defines the compute characteristics you need, including instance type, networking configuration, and scaling parameters.

When creating a capacity provider, you can choose from the latest generation of EC2 instances to match your workload requirements. For cost-optimized general-purpose compute, you could choose AWS Graviton4 based instances that deliver excellent price performance. If you’re not sure which instance type to select, AWS Lambda provides optimized defaults that balance performance and cost based on your function configuration.

After creating a capacity provider, you attach your Lambda functions to it through a straightforward configuration change. Before attaching a function, you should review your code for programming patterns that can cause issues in multiconcurrency environments, such as writing to or reading from file paths that aren’t unique per request or using shared memory spaces and variables across invocations.

Lambda automatically routes requests to preprovisioned execution environments on the instances, eliminating cold starts that can affect first-request latency. Each execution environment can handle multiple concurrent requests through the multiconcurrency feature, maximizing resource utilization across your functions. When additional capacity is needed during traffic increases, AWS automatically launches new instances within tens of seconds and adds them to your capacity provider. The capacity provider can absorb traffic spikes of up to 50% without needing to scale by default, but built-in circuit breakers protect your compute resources during extreme traffic surges by temporarily throttling requests with 429 status codes if the capacity provider reaches maximum provisioned capacity and additional capacity is still being spun up.

The operational and architectural model remains serverless throughout this process. AWS handles instance provisioning, OS patching, security updates, load balancing across instances, and automatic scaling based on demand. AWS automatically applies security patches and bug fixes to operating system and runtime components, often without disrupting running applications. Additionally, instances have a maximum 14-day lifetime to align with industry security and compliance standards. You don’t need to write automatic scaling policies, configure load balancers, or manage instance lifecycle yourself, and your function code, event source integrations, AWS Identity and Access Management (AWS IAM) permissions, and Amazon CloudWatch monitoring remain unchanged.

Now available
You can start using Lambda Managed Instances today through the Lambda console, AWS CLI, or AWS SDKs. The feature is available in US East (N. Virginia), US East (Ohio), US West (Oregon), Asia Pacific (Tokyo), and Europe (Ireland) Regions. For Regional availability and future roadmap, visit the AWS Capabilities by Region. Learn more about it in the AWS Lambda documentation.

Pricing for Lambda Managed Instances has three components. First, you pay standard Lambda request charges of $0.20 per million invocations. Second, you pay standard Amazon EC2 instance charges for the compute capacity provisioned. Your existing Amazon EC2 pricing agreements, including Compute Savings Plans and Reserved Instances, can be applied to these instance charges to reduce costs for steady-state workloads. Third, you pay a compute management fee of 15% calculated on the EC2 on-demand instance price to cover AWS’s operational management of your instances. Note that unlike traditional Lambda functions, you are not charged separately for execution duration per request. The multiconcurrency feature helps further optimize costs by reducing the total compute time required to process your requests.

The initial release supports the latest versions of Node.js, Java, .NET and Python runtimes, with support for other languages coming soon. The feature integrates with existing Lambda workflows including function versioning, aliases, AWS CloudWatch Lambda Insights, AWS AppConfig extensions, and deployment tools like AWS SAM and AWS CDK. You can migrate existing Lambda functions to Lambda Managed Instances without changing your function code (as long as it has been validated to be thread safe for multiconcurrency) making it easy to adopt this capability for workloads that would benefit from specialized compute or cost optimization.

Lambda Managed Instances represents a significant expansion of Lambda’s capabilities, which means you can run a broader range of workloads while preserving the serverless operational model. Whether you’re optimizing costs for high-traffic applications, or accessing the latest processor architectures like Graviton4, this new capability provides the flexibility you need without operational complexity. We’re excited to see what you build with Lambda Managed Instances.

Simplify IAM policy creation with IAM Policy Autopilot, a new open source MCP server for builders

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/simplify-iam-policy-creation-with-iam-policy-autopilot-a-new-open-source-mcp-server-for-builders/

Today, we’re announcing IAM Policy Autopilot, a new open source Model Context Protocol (MCP) server that analyzes your application code and helps your AI coding assistants generate AWS Identity and Access Management (IAM) identity-based policies. IAM Policy Autopilot accelerates initial development by providing builders with a starting point that they can review and further refine. It integrates with AI coding assistants such as Kiro, Claude Code, Cursor, and Cline, and it provides them with AWS Identity and Access Management (IAM) knowledge and understanding of the latest AWS services and features. IAM Policy Autopilot is available at no additional cost, runs locally, and you can get started by visiting our GitHub repository.

Amazon Web Services (AWS) applications require IAM policies for their roles. Builders on AWS, from developers to business leaders, engage with IAM as part of their workflow. Developers typically start with broader permissions and refine them over time, balancing rapid development with security. They often use AI coding assistants in hopes of accelerating development and authoring IAM permissions. However, these AI tools don’t fully understand the nuances of IAM and can miss permissions or suggest invalid actions. Builders seek solutions that provide reliable IAM knowledge, integrate with AI assistants and get them started with policy creation, so that they can focus on building applications.

Create valid policies with AWS knowledge
IAM Policy Autopilot addresses these challenges by generating identity-based IAM policies directly from your application code. Using deterministic code analysis, it creates reliable and valid policies, so you spend less time authoring and debugging permissions. IAM Policy Autopilot incorporates AWS knowledge, including published AWS service reference implementation, to stay up to date. It uses this information to understand how code and SDK calls map to IAM actions and stays current with the latest AWS services and operations.

The generated policies provide a starting point for you to review and scope down to implement least privilege permissions. As you modify your application code—whether adding new AWS service integrations or updating existing ones—you only need to run IAM Policy Autopilot again to get updated permissions.

Getting started with IAM Policy Autopilot
Developers can get started with IAM Policy Autopilot in minutes by downloading and integrating it with their workflow.

As an MCP server, IAM Policy Autopilot operates in the background as builders converse with their AI coding assistants. When your application needs IAM policies, your coding assistants can call IAM Policy Autopilot to analyze AWS SDK calls within your application and generate required identity-based IAM policies, providing you with necessary permissions to start with. After permissions are created, if you still encounter Access Denied errors during testing, the AI coding assistant invokes IAM Policy Autopilot to analyze the denial and propose targeted IAM policy fixes. After you review and approve the suggested changes, IAM Policy Autopilot updates the permissions.

You can also use IAM Policy Autopilot as a standalone command line interface (CLI) tool to generate policies directly or fix missing permissions. Both the CLI tool and the MCP server provide the same policy creation and troubleshooting capabilities, so you can choose the integration that best fits your workflow.

When using IAM Policy Autopilot, you should also understand the best practices to maximize its benefits. IAM Policy Autopilot generates identity-based policies and doesn’t create resource-based policies, permission boundaries, service control policies (SCPs) or resource control policies (RCPs). IAM Policy Autopilot generates policies that prioritize functionality over minimal permissions. You should always review the generated policies and refine if necessary so they align with your security requirements before deploying them.

Let’s try it out
To set up IAM Policy Autopilot, I first need to install it on my system. To do so, I just need to run a one-liner script:

curl https://github.com/awslabs/iam-policy-autopilot/raw/refs/heads/main/install.sh | bash

Then I can follow the instructions to install any MCP server for my IDE of choice. Today, I’m using Kiro!

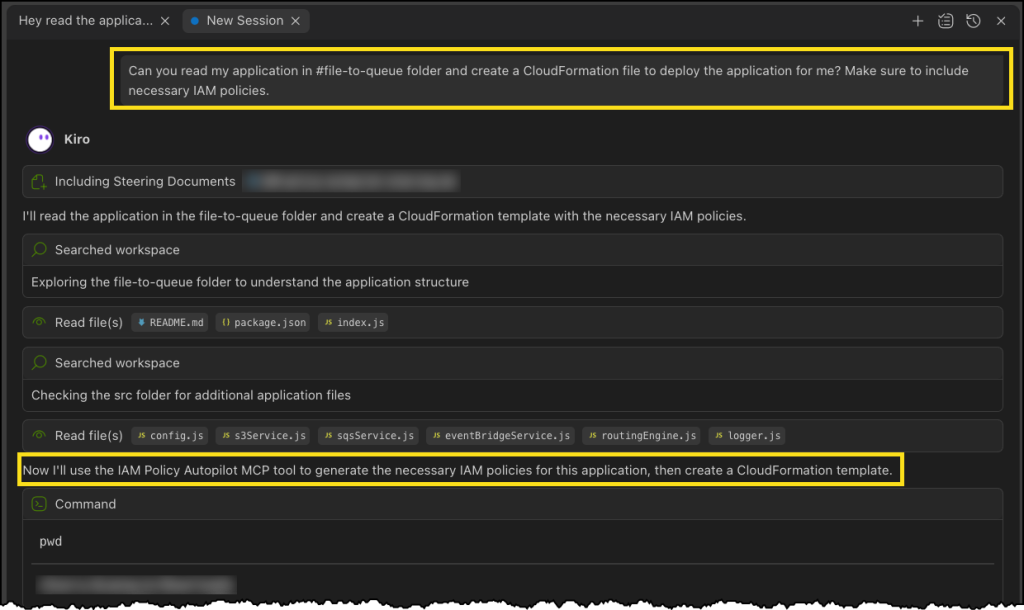
In a new chat session in Kiro, I start with a straightforward prompt, where I ask Kiro to read the files in my file-to-queue folder and create a new AWS CloudFormation file so I can deploy the application. This folder contains an automated Amazon Simple Storage Service (Amazon S3) file router that scans a bucket and sends notifications to Amazon Simple Queue Service (Amazon SQS) queues or Amazon EventBridge based on configurable prefix-matching rules, enabling event-driven workflows triggered by file locations.

The last part asks Kiro to make sure I’m including necessary IAM policies. This should be enough to get Kiro to use the IAM Policy Autopilot MCP server.

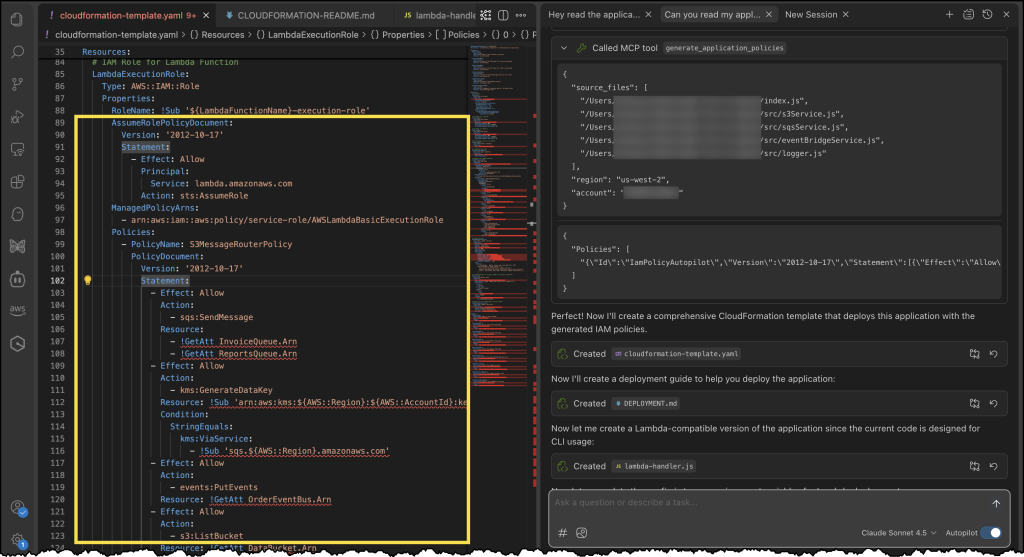
Next, Kiro uses the IAM Policy Autopilot MCP server to generate a new policy document, as depicted in the following image. After it’s done, Kiro will move on to building out our CloudFormation template and some additional documentation and relevant code files.

IAM Policy Autopilot

Finally, we can see our generated CloudFormation template with a new policy document, all generated using the IAM Policy Autopilot MCP server!

IAM Policy Autopilot

Enhanced development workflow
IAM Policy Autopilot integrates with AWS services across multiple areas. For core AWS services, IAM Policy Autopilot analyzes your application’s usage of services such as Amazon S3, AWS Lambda, Amazon DynamoDB, Amazon Elastic Compute Cloud (Amazon EC2), and Amazon CloudWatch Logs, then generates necessary permissions your code needs based on the SDK calls it discovers. After the policies are created, you can copy the policy directly into your CloudFormation template, AWS Cloud Development Kit (AWS CDK) stack, or Terraform configuration. You can also prompt your AI coding assistants to integrate it for you.

IAM Policy Autopilot also complements existing IAM tools such as AWS IAM Access Analyzer by providing functional policies as a starting point, which you can then validate using IAM Access Analyzer policy validation or refine over time with unused access analysis.

Now available
IAM Policy Autopilot is available as an open source tool on GitHub at no additional cost. The tool currently supports Python, TypeScript, and Go applications.

These capabilities represent a significant step forward in simplifying the AWS development experience so builders of different experience levels can develop and deploy applications more efficiently.

Your Guide to the Developer Tools Track at AWS re:Invent 2025

Post Syndicated from Brian Beach original https://aws.amazon.com/blogs/devops/your-guide-to-the-developer-tools-track-at-aws-reinvent-2025/

AWS re:Invent 2025 is just around the corner, and if you’re a developer looking to level up your skills, the Developer Tool (DVT) track has an incredible lineup waiting for you. From CI/CD pipelines and full-stack development to Infrastructure as Code and AI-powered coding agents, this year’s sessions will help you build faster, smarter, and more efficiently. Here’s your essential guide to navigating the week.

Must-Attend Sessions

AWS re:Invent is a learning focused conference and the best place for developer to learn is in one of the roughly 75 sessions on the Developer Tools track. With breakout sessions, lightening talks, chalk talks, code talks, workshops, builder sessions, and meetups, you are sure to find a something that appeals the developer in you. Check you the event catalog, or start with these stand out sessions.

  • DVT202: Continuous integration and continuous delivery (CI/CD) on AWS – Learn about creating complete CI/CD pipelines using infrastructure as code on AWS, with hands-on insights into planning work, collaborating on code, and deploying applications. Mandalay Bay – Monday 10:00 AM
  • DVT203: AWS infrastructure as code: A year in review – Discover the latest features and improvements for AWS CloudFormation and AWS CDK, and learn how these tools can bring rigor, clarity, and reliability to your application development. MGM Grand – Monday 10:30 AM
  • DVT204: What’s new in full-stack AWS app development – Find out how AWS is evolving to help web developers deliver differentiating experiences at 10x speed with solutions that empower you to get started easily, ship quickly, and iterate rapidly. Mandalay Bay – Monday 12:00 PM
  • DVT209: Kiro: Your agentic IDE for spec-driven development – Explore how Kiro is revolutionizing development with spec-driven workflows, agent hooks, multimodal agent chat, and MCP support to help you go from idea to production faster. MGM Grand – Wednesday 11:30 AM
  • DVT405: From Code completion to autonomous agents: The evolution of software development – Journey through the evolution of AI-powered coding agents from inline code completion to sophisticated autonomous tools, grounded in empirical evidence and real-world applications. MGM Grand – Wednesday 3:00 PM
  • DVT207: Developer experience economics: moving past productivity metrics – Learn Amazon’s approach to understanding the impact of developer experience and tooling, and discover how to bring strategic thinking to your team’s developer experience improvements. Mandalay Bay – Tuesday 5:30 PM

House of Kiro

Start your journey at the House of Kiro in the Venetian. Walk through Kiro’s haunted house filled with developer nightmares and horrors, and explore how Kiro brings structure to coding chaos through spec-driven development, vibe coding, and agent hooks. If you survive the haunted house, you will be rewarded with Kiro swag.

Rustic wooden cabin structure with "KIRO" branding and ghost logo on the roof, featuring boarded-up windows with glowing purple light emanating from behind, creating a haunted house aesthetic with a front porch and chimney.

AWS Village

Visit the AWS Village in the Expo at the Venetian Level 2 Hall B to speak with me and other experts at either the Kiro kiosk or the Developer Tools kiosk, covering CodePipeline, CodeBuild, CloudFormation, CDK, and all the essential developer tools.

  • The Venetian, Monday, Dec 1: 4:00 PM – 7:00 PM
  • Tuesday, Dec 2: 10:00 AM – 6:00 PM
  • Wednesday, Dec 3: 10:00 AM – 6:00 PM
  • Thursday, Dec 4: 10:00 AM – 4:00 PM

AWS booth at a conference or trade show featuring the iconic AWS logo and smile design suspended above a multi-level exhibition space with purple and blue gradient lighting, surrounded by attendees exploring various demo stations.

Builders Loft

Located at the south end of the strip in Mandalay Bay, the Builders Loft offers a collaborative workspace with dedicated co-working spaces and meetup zones. Enjoy coffee, snacks, SWAG, and daily tech challenges for a chance to win AWS credits. Kiro experts will be at the builders loft Monday-Thursday:

  • 8:00 AM – 12:00 PM: Co-working space for one-on-one consultations
  • 12:00 PM – 1:00 PM: Daily meetup in the meetup space
  • 4:50 PM – 5:00 PM: Q&A in the whiteboard section

Isometric 3D rendering of an AWS re:Invent expo floor layout featuring purple and pink branded kiosks, blue seating areas with round tables, interactive display stations, and workspace zones in a modern conference environment.

Hands-On Challenges

Kiro’s Labyrinth

Stop by the Kiro kiosk in the Venetian Expo to participate in Kiro’s Labyrinth, a coding challenge where you’ll help Kiro escape from a spooky Halloween maze and win prizes. The Kiro code champions will be crowned in DVT221 at Mandalay Bay on Thursday at 11:30 AM.

Atmospheric 3D render of a medieval dungeon or castle interior with dramatic red and orange lighting from wall-mounted torches, featuring stone archways, staircases, cobblestone floors, and blue accent lighting creating a moody gaming environment.

Kiroween Hackathon

Build something wicked for Kiroween, the annual hackathon that started on Halloween and ends on Friday, December 5th—the last day of re:Invent. Need help? Visit us at in the Builder Loft in Mandalay Bay: Monday-Friday, 8:30 AM – 12:00 PM or the Developer Pavilion in Venetian whenever the Expo is open.

Purple banner with "KIROWEEN" text in white, flanked by three ghost characters including the Kiro ghost mascot, a mummy ghost, and a skeleton ghost, creating aHalloween-themed branding element.

Conclusion

Make the most of your re:Invent experience by attending these sessions, connecting with experts at the AWS Village and Builders Loft, and participating in hands-on challenges. Whether you’re interested in CI/CD, infrastructure as code, AI-powered development, or just want to network with fellow builders, the Developer Tools track has something for everyone. See you in Vegas!

Code Club Conference 2025: Creativity, community, and collaboration in Cambridge

Post Syndicated from Sarah Lygoe original https://www.raspberrypi.org/blog/code-club-conference-2025-creativity-community-and-collaboration-in-cambridge/

Over the first weekend in November, members of the global Code Club community came together for two inspiring days of learning, creativity and connection. The annual event celebrates the people who make Code Clubs happen, allowing them to share ideas, explore new tools, and connect with others who help young people learn to code.

Educator at Code Club Conference attending a workshop

Exploring new technologies and inclusive teaching

Saturday began with hands-on sessions that brought creativity and technology together, exploring large language models and prompt engineering in Collaborating with LLMs and being a prompt boss. There was a lot of laughter from attendees about how large language models can produce confident but incorrect answers if given vague prompts, but many left inspired to experiment with new technologies in their own clubs.

“First time there and it was amazing. Met loads of great people and the amazing code club crew. I learnt loads of new skills around AI and Arduino.” – An attendee

Explore AI with creators in your club using our AI and machine learning projects.

Educator in a workshop, using a micro:bit

Collaboration that counts brought mentors together to discuss common challenges like volunteer retention, limited resources, and communication barriers. A crowd favourite was a shared volunteer toolkit, as well as event checklists and safeguarding resources.

“What I enjoyed most about the Clubs Conference was the opportunity to meet other facilitators and hear their stories — their successes and challenges. These conversations validated the volunteer work I do and reminded me of the impact of our clubs.” – An attendee

From the theatre sessions, you can watch Inclusive learning – Supporting Deaf learners in clubs which was both moving and insightful. We learnt that visual demonstrations, colour cues, and repetition were key to supporting Deaf learners. One memorable quote captured the spirit of the session:

“The children couldn’t speak to us. The children — we couldn’t hear their voices but by the eighth week we were able to hear their voices from what they built on the screen and it was echoing all around the classroom.” – Chidi Duru

Find out more about Chidi’s joy of coding alongside Deaf creators.

Learning and making across continents

The weekend’s talks showcased the reach of Code Club worldwide, with volunteers sharing their experiences of collaboration, sustainability, and creativity.

Watch Lessons from resourceful Code Clubs in India, which highlighted the ingenuity of young learners in under-resourced settings, while Hands-on with the Raspberry Pi Pico showcased low-cost, high-impact projects from Kenya and South Africa.

Speakers showed how community clubs adapt to local needs with unplugged activities and coding games inspired by cricket and kabaddi, empowering young people to solve real problems and celebrate curiosity through play. Excitingly, these new resources will be launching early next year; keep an eye on our activities page to be among the first to try them out!

Two attendees during a workshop working together

In the session Code Club Projects Unplugged, facilitators shared the idea of “hiding the vegetables” — hiding the learning inside the fun. Whether through a collaborative Scratch game, a micro:bit prop on stage, or a Pico gadget solving a real problem, this approach helps young people learn through play. They remember the joy, and the skills come naturally.

Learning beyond the screen

Teaching tech away from the computer screen shared a fun unplugged cybersecurity activity, The Chicken Shop, where learners role-play social engineering scenarios. Its success came from clear printed instructions, movement, humour, and strong debriefing. 

Educators sharing ideas during a workshop

Learning coding outside the box explored how to engage young people with diverse learning styles while the Arduino crash course gave attendees a taste of physical computing and C++ programming in action. Workshops on AI, sustainability, and youth empowerment with Raspberry Pi computers and Unlocking Code Club resources helped club leaders discover practical ways to inspire problem-solving and make use of all the support available through Code Club.

The message from the sessions was clear: young people learn best when technology is human and hands-on.

Showcasing creativity with Coolest Projects

Coolest Projects – get involved! championed creativity over competition. Any young person under 18 can submit their project, including unfinished ideas. In-person and online showcases celebrate progress, imagination, and teamwork.

Speaking on the closing panel, Code Club leader Rachael Coultart talked about the importance of Coolest Projects as a rare platform for children to talk about their learning. She spoke about the experience of one particular child, explaining that it had made a powerful impression on her, saying:

“It had such a huge impact. I felt so proud of her and what she’d achieved. Afterwards, her parents told me that they felt it was the first time she had really been seen.”

What the community is taking forward

The community is united in its commitment to making Code Clubs inclusive, creative, and sustainable. 

  • Context matters — projects that reflect local interests and challenges motivate young people to learn
  • Accessibility is central: visual cues, repetition, interpreters, and inclusive resources support every learner
  • Structure builds confidence; start with simple, guided activities before open-ended exploration
  • Volunteers are vital; shared toolkits, checklists, and training help them deliver engaging sessions
  • Celebration and affordability matter too: regular showcases and tools like the micro:bit, Pico, and Crumble keep computing fun, hands-on, and accessible for all

“Thank you. Clubs Conference is a highlight of my year.” – An attendee

Stay connected

If you want to stay up to date with the latest news, events and opportunities from Code Club, sign up for our newsletter and be part of the growing global community.

The post Code Club Conference 2025: Creativity, community, and collaboration in Cambridge appeared first on Raspberry Pi Foundation.

Your guide to AWS Analytics at AWS re:Invent 2025

Post Syndicated from Sonu Kumar Singh original https://aws.amazon.com/blogs/big-data/your-guide-to-aws-analytics-at-aws-reinvent-2025/

re:Invent banner

It’s that time of year again — AWS re:Invent is here! At re:Invent, bold ideas come to life. Get a front-row seat to hear inspiring stories from AWS experts, customers, and leaders as they explore today’s most impactful topics, from data analytics to AI.

For all the data enthusiasts and professionals, we’ve curated a comprehensive guide to every analytics session to help you plan your perfect agenda. Make sure to secure your seat early for must-attend sessions via the attendee portal.

Pro tip: Even if a session shows as fully reserved, we encourage you to join the walk-up line at the session location. Based on previous years’ experiences, additional seats often become available due to no-shows or last-minute schedule changes. The walk-up line operates on a first-come, first-served basis, and many attendees have successfully accessed their desired sessions this way. Just be sure to arrive at least 15 minutes before the session starts for the best chance of getting a seat.

Can’t make it in person? No problem — grab a free virtual pass to stream live sessions from anywhere.

And don’t forget to stop by the AWS Kiosk in the AWS Village Expo for AWS Analytics, Amazon SageMaker, Amazon OpenSearch Service and AWS Messaging and Streaming services! See live demos of analytics services, meet AWS experts, get your toughest data questions answered, explore the latest launches, join our data trivia, and even win exclusive AWS-authored books and many more swags.

Data Innovation Talk

INV201 | Harnessing analytics for humans and AI

Emerging trends, ranging from Open Table Formats (OTF) to agentic infrastructure, are rapidly changing how humans and applications interact with analytics to drive mission-critical business decisions. Join Mai-Lan Tomsen Bukovec, VP of AWS Technology, to explore emerging trends, the evolution of analytics engines and applications, and how to future-proof your data foundation for the rapidly changing landscape of analytics at scale. Learn how AWS is transforming data and analytics services to lead in optimized data storage, querying, streaming, processing, and governance – for both human users and agentic infrastructure.

Breakouts

Dive into cutting-edge topics with re:Invent breakout sessions. These immersive, hour-long lectures are led by AWS experts, customers, offering you unparalleled insights and knowledge in a concise format. Whether you’re exploring the latest in cloud technology, AWS Analytics advancements, or industry-specific solutions, these sessions are designed to expand your horizon and inspire your next big idea.

Monday, Dec 1 Tuesday, Dec 2 Wednesday, Dec 3 Thursday, Dec 4
8:30 AM – 9:30 AM PST | Venetian | Level 3 | Lido 3106

ANT203 | Enabling AI innovation with Amazon SageMaker Unified Studio

11:30 AM – 12:30 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Turquoise Theater

BIZ207 | Democratize access to insights with Amazon Quick Suite

8:30 AM – 9:30 AM PST | MGM | Level 1 | Grand 123

ANT204 | Architecting the future: Amazon SageMaker as a data and AI platform

11:00 AM – 12:00 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Pink Theater

ANT317 | Modernize your data warehouse by moving to Amazon Redshift

8:30 AM – 9:30 AM PST | MGM | Level 3 | Chairman’s 366

ANT318 | Scaling Amazon Redshift with a multi-warehouse architecture

11:30 AM – 12:30 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Pink Theater

ANT216 | What’s new with Amazon SageMaker in the era of unified data and AI

10:00 AM – 11:00 AM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Turquoise Theater

ANT335 | Agentic data engineering with AWS Analytics MCP Servers

11:30 AM – 12:30 PM PST | Wynn | Upper Convention Promenade | Cristal 7

ANT328 | Data Processing architectures for building AI solutions

9:00 AM – 10:00 AM PST | Wynn | Convention Promenade | Lafite 7 | Content Hub | Mint Green Theater

ANT307 | Operating Apache Kafka and Apache Flink at scale

1:30 PM – 2:30 PM PST | MGM | Level 3 | Chairman’s 364

BIZ203 | Amazon’s journey deploying Quick Suite across thousands of users

10:00 AM – 11:00 AM PST | Wynn | Upper Convention Promenade | Bollinger

ANT304 | Build an AI-ready data foundation

1:00 PM – 2:00 PM PST | MGM | Level 1 | Grand 122

BIZ227 | Generate new revenue streams with Amazon Quick Sight embedded

10:00 AM – 11:00 AM PST | Wynn | Upper Convention Promenade | Bollinger

BIZ331 | Build robust data foundations to power enterprise AI and BI

1:30 PM – 2:30 PM PST | Wynn | Convention Promenade | Lafite 7 | Content Hub | Mint Green Theater

ANT206 | What’s new in Amazon Redshift and Amazon Athena

11:30 AM – 12:30 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Turquoise Theater

ANT424 | Autonomous agents powered by streaming data and Retrieval Augmented Generation

2:00 PM – 3:00 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Turquoise Theater

ANT343 | Best practices for building Apache Iceberg based lakehouse architectures on AWS

10:00 AM – 11:00 AM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Pink Theater

ANT209 | Universal data connectivity with ETL and SQL queries

4:00 PM – 5:00 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Turquoise Theater

ANT308 | Explore what’s new in data and AI governance with SageMaker Catalog

11:30 AM – 12:30 PM PST | Wynn | Convention Promenade | Lafite 7 | Content Hub | Pink Theater

ANT310 | Powering your Agentic AI experience with AWS Streaming and Messaging

4:00 PM – 5:00 PM PST | Mandalay Bay | Level 3 South | South Seas E

ANT344 | Build, govern, and share Amazon Quick Suite dashboards with Amazon SageMaker

10:30 AM – 11:30 AM PST | MGM | Level 1 | Grand 116

ANT314 | Build Advanced Search with Vector, Hybrid, and AI Techniques

4:30 PM – 5:30 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Mint Green Theater

ANT305 | Innovations in AWS analytics: Data processing

2:30 PM – 3:30 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Pink Theater

ANT315 | Intelligent Observability and Modernization with Amazon OpenSearch Service

4:00 PM – 5:00 PM PST | Wynn | Convention Promenade | Lafite 7 | Content Hub | Orange Theater

DAT445 | Deep dive into databases zero-ETL integrations

12:00 PM – 1:00 PM PST | MGM | Level 3 | Chairman’s 360

ANT336 | Enterprise-scale ETL optimization for Apache Spark

. 3:00 PM – 4:00 PM PST | MGM | Level 1 | Grand 122

ANT309 | Accelerate analytics and AI with an open and secure lakehouse architecture

.
12:00 PM – 1:00 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Orange Theater

ANT339 | Turn unstructured data in Amazon S3 into AI-ready assets with SageMaker Catalog

. . .
1:00 PM – 2:00 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Pink Theater

ANT201 | What’s new in search, observability, and vector databases with OpenSearch

. . .
1:30 PM – 2:30 PM PST | Wynn | Convention Promenade | Lafite 7 | Content Hub | Orange Theater

BIZ228 | Reimagine business intelligence with Amazon Quick Sight

. . .
1:30 PM – 2:30 PM PST | Mandalay Bay | Level 3 South | South Seas E

OPN413 | Transforming Apache Kafka into a Scalable Message Queue

. . .
5:30 PM – 6:30 PM PST | Mandalay Bay | Level 3 South | South Seas F

ANT423 | Amazon Kinesis Data Streams under the hood

. . .

Chalk talks

These hour-long, highly engaging sessions offer a unique blend of expert insight and collaborative learning. An AWS specialist kicks off with a concise, informative lecture, setting the stage for an in-depth, interactive Q&A. With a limited audience size, you’ll have the opportunity to dive deep into topics, ask pressing questions, and engage in meaningful discussions with both the presenter and fellow attendees.

Monday, Dec 1 Tuesday, Dec 2 Wednesday, Dec 3 Thursday, Dec 4 Friday, Dec 5
8:30 AM – 9:30 AM PST | MGM | Level 1 | Boulevard 167

ANT301-R1 | Accelerating the shift from batch to real-time streaming

11:30 AM – 12:30 PM PST | Caesars Forum | Level 1 | Academy 411

ANT302-R1 | Accelerate GenAI-powered data discovery and sharing with SageMaker Catalog

9:00 AM – 10:00 AM PST | MGM | Level 3 | Room 353

ANT301-R | Accelerating the shift from batch to real-time streaming

11:30 AM – 12:30 PM PST | MGM | Level 3 | Room 353

ANT207 | Develop with natural language and agentic AI in Amazon SageMaker Unified Studio

10:30 AM – 11:30 AM PST | Caesars Forum | Level 1 | Summit 221

ANT331 | Optimize Cost and Performance in Amazon OpenSearch Service

8:30 AM – 9:30 AM PST | Mandalay Bay | Level 2 South | Reef C

ANT347 | Build a secure and regulated data foundation for AI

11:30 AM – 12:30 PM PST | Mandalay Bay | Level 3 South | South Seas A

ANT217 | Build data pipelines in minutes with the Amazon SageMaker Visual experience

9:00 AM – 10:00 AM PST | Mandalay Bay | Level 3 South | South Seas H

ANT319-R1 | Optimizing Apache Spark workloads with AWS Analytics

12:30 PM – 1:30 PM PST | Mandalay Bay | Level 3 South | South Seas A

ANT346 | Architectural blueprints for your lakehouse in Amazon SageMaker

.
10:00 AM – 11:00 AM PST | Mandalay Bay | Level 3 South | South Seas A

ANT420-R | AI-driven scaling in Amazon Redshift Serverless

12:00 PM – 1:00 PM PST | Caesars Forum | Level 1 | Alliance 305

ANT301-R2 | Accelerating the shift from batch to real-time streaming

10:00 AM – 11:00 AM PST | MGM | Level 1 | Boulevard 158

ANT321 | Top 10 tips to improve query performance in Amazon Redshift

2:00 PM – 3:00 PM PST | MGM | Level 1 | Room 101

ANT303 | Implement data pipelines for analytics using Amazon SageMaker Unified Studio

.
10:30 AM – 11:30 AM PST | Wynn | Convention Promenade | Latour 5

ANT302-R | Accelerate GenAI-powered data discovery and sharing with SageMaker Catalog

1:00 PM – 2:00 PM PST | Mandalay Bay | Level 2 South | Lagoon G

ANT330-R | Design and build Intelligent Observability with Amazon OpenSearch Service

10:00 AM – 11:00 AM PST | Wynn | Convention Promenade | La Tache 2

ANT320 | Strengthening security for Apache Spark workloads

2:00 PM – 3:00 PM PST | Mandalay Bay | Level 3 South | South Seas J

ANT322 | Architectural patterns for real-time data analytics on AWS

.
11:30 AM – 12:30 PM PST | Mandalay Bay | Level 3 South | South Seas A

ANT338 | Bring unified analytics to your data warehouse with the lakehouse architecture

1:30 PM – 2:30 PM PST | MGM | Level 3 | Premier 320

ANT325-R1 | A deep dive into AI/ML development in SageMaker Unified Studio

11:30 AM – 12:30 PM PST | Mandalay Bay | Level 3 South | South Seas C

ANT332 | Building high-quality data products for AI Agents

3:30 PM – 4:30 PM PST | MGM | Level 1 | Room 101

ANT337 | Breaking data silos with the lakehouse architecture

.
11:30 AM – 12:30 PM PST | Wynn | Convention Promenade | Montrachet 1

BIZ323 | Design AI-powered BI architectures for modern enterprises with Amazon Quick Suite

2:30 PM – 3:30 PM PST | Mandalay Bay | Level 2 South | Lagoon G

ANT420-R1 | AI-driven scaling in Amazon Redshift Serverless

1:00 PM – 2:00 PM PST | Mandalay Bay | Level 3 South | South Seas C

ANT340 | Deep dive into data processing in SageMaker Unified Studio

. .
1:30 PM – 2:30 PM PST | MGM | Level 3 | Room 353

ANT325-R | A deep dive into AI/ML development in SageMaker Unified Studio

2:30 PM – 3:30 PM PST | Mandalay Bay | Lower Level North | South Pacific B

ANT341 | Build trust in AI with end-to-end data lineage in Amazon SageMaker Catalog

2:30 PM – 3:30 PM PST | MGM | Level 3 | Chairman’s 356

ANT345 | Building secure and scalable lakehouses for the future

. .
2:30 PM – 3:30 PM PST | Mandalay Bay | Level 3 South | South Seas A

ANT329 | Build Advanced AI-powered Search with OpenSearch MCP and Vectors

2:30 PM – 3:30 PM PST | Mandalay Bay | Level 3 South | South Seas C

BIZ327 | Bridge data silos to unlock complete insights with Amazon Quick Suite

2:30 PM – 3:30 PM PST | Mandalay Bay | Level 3 South | South Seas J

ANT413 | Upgrade Amazon DataZone to Amazon SageMaker Catalog for analytics and AI

. .
3:00 PM – 4:00 PM PST | MGM | Level 3 | Premier 320

BIZ319 | Beyond chatbots: Discover conversational AI in Amazon Quick Suite

3:00 PM – 4:00 PM PST | Wynn | Convention Promenade | Latour 5

ANT421 | Advanced Stream Processing with Apache Flink

4:00 PM – 5:00 PM PST | MGM | Level 3 | Room 350

ANT324 | Building Pipelines for Analytics, ML and AI in Amazon Sagemaker Unified Studio

. .
4:00 PM – 5:00 PM PST | MGM | Level 3 | Chairman’s 356

ANT422 | Building Resilient Multi-Tenant Messaging with Amazon SQS

4:00 PM – 5:00 PM PST | Mandalay Bay | Level 2 South | Reef C

ANT319-R | Optimizing Apache Spark workloads with AWS Analytics

4:00 PM – 5:00 PM PST | Mandalay Bay | Level 3 South | South Seas C

ANT323 | Mastering materialized views: tips for fast, low-latency queries in Redshift

. .
4:30 PM – 5:30 PM PST | Caesars Forum | Level 1 | Alliance 305

ANT330-R1 | Design and build Intelligent Observability with Amazon OpenSearch Service

5:30 PM – 6:30 PM PST | MGM | Level 3 | Room 350

ANT326 | Mastering data transformations with Amazon Athena

5:30 PM – 6:30 PM PST | MGM | Level 1 | Boulevard 167

ANT316 | Orchestrating with Apache Airflow, MWAA, and SageMaker Unified Studio

Builders’ sessions

Immerse yourself in our builders’ sessions – a hands-on learning experience designed to elevate your AWS skills. These focused, hour-long workshops bring together a small group of up to ten attendees with a dedicated AWS expert at each table.

Monday, Dec 1 Tuesday, Dec 2 Wednesday, Dec 3 Thursday, Dec 4
8:30 AM – 9:30 AM PST | Wynn | Convention Promenade | Latour 7

ANT407-R1 | Building event-driven applications with AWS Streaming and Messaging

11:30 AM – 12:30 PM PST | MGM | Level 1 | Room 104

ANT415 | Securely monetize your data with Amazon Redshift

1:00 PM – 2:00 PM PST | Mandalay Bay | Lower Level North | Islander H

ANT407-R | Building event-driven applications with AWS Streaming and Messaging

12:30 PM – 1:30 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Builders’ Session 1

ANT409 | Getting hands on with zero-ETL and data federation

11:30 AM – 12:30 AM PST | MGM | Level 1 | Room 104

ANT410-R | Integrate and orchestrate data workflows with AWS Glue & MWAA

2:30 PM – 3:30 PM PST | MGM | Level 3 | Room 304

ANT405-R1 | Build high performance Apache Iceberg data lakes with Amazon S3 Tables

1:00 PM – 2:00 PM PST | Wynn | Convention Promenade | Latour 7

ANT406-R | Build trust in your data with Amazon SageMaker Catalog

2:00 PM – 3:00 PM PST | Mandalay Bay | Lower Level North | Islander H

ANT419-R | Vector search with Amazon OpenSearch Service

11:30 AM – 12:30 PM PST | Wynn | Convention Promenade | Latour 7

ANT406-R1 | Build trust in your data with Amazon SageMaker Catalog

4:30 PM – 5:30 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Builders’ Session 2

ANT410-R1 | Integrate and orchestrate data workflows with AWS Glue & MWAA

4:00 PM – 5:00 PM PST | MGM | Level 3 | Room 304

ANT419-R1 | Vector search with Amazon OpenSearch Service

3:30 PM – 4:30 PM PST | Caesars Forum | Level 1 | Alliance 315

OPN407-R1 | Performance tuning for streaming Ingestion into Apache Iceberg

2:30 PM – 3:30 PM PST | MGM | Level 1 | Room 104

ANT408 | Data analytics for financial organizations with Amazon SageMaker

. . .
3:00 PM – 4:00 PM PST | Caesars Forum | Level 1 | Alliance 311

OPN407-R | Performance tuning for streaming Ingestion into Apache Iceberg

. . .
4:00 PM – 5:00 PM PST | Mandalay Bay | Lower Level North | Islander H

ANT405-R | Build high performance Apache Iceberg data lakes with Amazon S3 Tables

. . .

Workshops

Roll your sleeves in our dynamic 2-hour workshops, where you’ll tackle real-world challenges using AWS services. These interactive sessions kick off with a brief, informative lecture to set the stage, then quickly transition into hands-on problem-solving. Bring your laptop and prepare to build alongside AWS experts, who will guide you through practical applications of cloud computing concepts. Whether you’re new to AWS or looking to sharpen your skills, these workshops offer a unique opportunity to learn by doing, enabling you to leave with confidence and applicable knowledge in AWS technologies.

Monday, Dec 1 Tuesday, Dec 2 Wednesday, Dec 3 Thursday, Dec 4
8:00 AM – 10:00 AM PST | Mandalay Bay | Lower Level North | Islander C

ANT402-R1 | Build a fraud detection system with Amazon SageMaker Unified Studio

12:00 PM – 2:00 PM PST | MGM | Level 3 | Premier 317

ANT418 | Unleash Apache Kafka’s elasticity and cost-efficiency with Amazon MSK

8:30 AM – 10:30 AM PST | Mandalay Bay | Lower Level North | Islander C

ANT402-R | Build a fraud detection system with Amazon SageMaker Unified Studio

12:00 PM – 2:00 PM PST | MGM | Level 3 | Premier 317

ANT412 | Power streaming analytics on AWS with AI-driven insights

8:00 AM – 10:00 AM PST | Mandalay Bay | Level 2 South | Mandalay Bay Ballroom H

ANT403 | Building Production-Ready Data Systems for AI Applications

12:30 PM – 2:30 PM PST | MGM | Level 3 | Chairman’s 368

ANT404-R1 | Build modern data applications with the lakehouse architecture on AWS

8:30 AM – 10:30 AM PST | Caesars Forum | Level 1 | Alliance 308

BIZ204-R1 | Experience AI-powered BI with Amazon Quick Suite

3:00 PM – 5:00 PM PST | Mandalay Bay | Lower Level North | Islander C

ANT416 | Solve complex data and AI governance challenges with Amazon SageMaker Catalog

8:30 AM – 10:30 AM PST | Wynn | Upper Convention Promenade | Cristal 3

BIZ306 | Create agentic AI chat experiences with Amazon Quick Suite

3:00 PM – 5:00 PM PST | Mandalay Bay | Level 2 South | Mandalay Bay Ballroom K

ANT411 | Low-cost logging and observability with Amazon OpenSearch Service

12:30 PM – 2:30 PM PST | MGM | Level 1 | Grand 113

ANT404-R | Build modern data applications with the lakehouse architecture on AWS

.
12:00 PM – 2:00 PM PST | MGM | Level 3 | Premier 317

ANT417 | Simplifying data interoperability with the lakehouse architecture on AWS

3:00 PM – 5:00 PM PST | Wynn | Upper Convention Promenade | Cristal 1

BIZ204-R | Experience AI-powered BI with Amazon Quick Suite

3:30 PM – 5:30 PM PST | Mandalay Bay | Lower Level North | Islander C

ANT401 | Build an AI-powered enterprise search with Amazon OpenSearch service

.
3:00 PM – 5:00 PM PST | Mandalay Bay | Level 2 South | Mandalay Bay Ballroom K

ANT414 | Scale intelligent analytics with Amazon Redshift multi-cluster architectures

. . .

Lightning Talks

Located in the Expo Hall, each of these 20-minute theater presentations are dedicated to a specific customer story, service demo, or AWS Partner offering.

Monday, Dec 1 Tuesday, Dec 2 Wednesday, Dec 3 Thursday, Dec 4
5:00 PM – 5:20 PM PST | Venetian | Level 2 | Hall B | Expo | Theater 4

ANT334 | High-performance NLP & geospatial analysis with Redshift

. 3:00 PM – 3:20 PM PST | Mandalay Bay | Level 2 South | Oceanside C | Content Hub | Lightning Theater

ANT333 | Fast-track to insights: AWS-SAP data strategy

12:30 PM – 12:50 PM PST | Venetian | Level 2 | Hall B | Expo | Theater 3

ANT342 | ITTI’s Cross-Company Data Mesh Blueprint with Amazon SageMaker

6:00 PM – 6:20 PM PST | Venetian | Level 2 | Hall B | Expo | Theater 3

ANT348 | Seamless data sharing in Amazon Redshift

. . .

Conclusion

We hope this post acts as your go-to resource for navigating the AWS analytics track at re:Invent 2025. For staying in the know about the most recent trends and advancements in AWS Analytics, follow our LinkedIn page.


About the authors

Navnit Shukla

Navnit Shukla

Navnit serves as an AWS Specialist Solutions Architect with a focus on Data and AI. He possesses a strong enthusiasm for assisting clients in discovering valuable insights from their data. Through his expertise, he constructs innovative solutions that empower businesses to arrive at informed, data-driven choices. Notably, he is the author of Data Wrangling on AWS and co-author of AI-Ready Data Blueprints with O’Reilly.

Sonu Kumar Singh

Sonu Kumar Singh

Sonu is a Senior Solutions Architect with over 13 years of experience, with a specialization in Analytics and Healthcare domain. He has been instrumental in catalyzing transformative shifts in organizations by enabling data-driven decision-making thereby fueling innovation and growth. He enjoys it when something he designed or created brings a positive impact.

The attendee’s guide to the AWS re:Invent 2025 Compute track

Post Syndicated from Mai Kulkarni original https://aws.amazon.com/blogs/compute/the-attendees-guide-to-the-aws-reinvent-2025-compute-track/

From December 1st to December 5th, Amazon Web Services (AWS) will hold its annual premier learning event: re:Invent. At this event, attendees can become stronger and more proficient in any area of AWS technology through a variety of experiences: large keynotes given by AWS leaders, smaller innovation talks, interactive working sessions given by AWS experts, and fun activities such as live music and games at re:Play.

There are over 2000+ learning sessions that focus on specific topics at various skill levels, and the compute team have created 76 unique sessions for you to choose. There are many sessions you can choose from, and we are here to help you choose the sessions that best fit your needs. Even if you cannot join in person, you can catch-up with many of the sessions on-demand and even watch the keynote and innovation sessions live.

The basics: Session types

If you can join us, then remember that we offer several types of sessions that can help maximize your learning in a variety of AWS topics.

re:Invent attendees can also choose to attend chalk-talks, builder sessions, workshops, or code talk sessions. Each of these are live non-recorded interactive sessions.

  • Breakout sessions: Attendees are in a lecture-style 60-minute informative sessions presented by AWS experts, customers, or partners. These sessions are recorded and uploaded a few days after to the AWS Events YouTube channel.
  • Chalk-talk sessions: Attendees interact with presenters, asking questions, and using a whiteboard in session.
  • Builder Sessions: Attendees participate in a one-hour session and build something.
  • Workshops sessions: Attendees join a two-hour interactive session where they work in a small team to solve a real problem using AWS services.
  • Code talk sessions: Attendees participate in engaging code-focused sessions where an expert leads a live coding session.
  • Lightning talk sessions: Attendees watch a 20-minute demo dedicated to either a specific service or customer story (located in the Venetian Expo Hall or Mandalay Bay Level 2 South).

Getting started with Amazon EC2

The foundation of compute in AWS is Amazon Elastic Compute Cloud (Amazon EC2). Amazon EC2 offers the broadest and deepest compute platform, with over 1000 instances and choice of the latest processor, storage, networking, operating system, and purchase model to help you best match the needs of your workload. We’ve created the following sessions to help you implement and manage your workloads on EC2.

CMP356 | How well do you know EC2

EC2 offers 1000+ instance types with diverse processors, accelerators, and the AWS Nitro System. Options include cost-effective Spot Instances and Savings Plans. Learn how to optimize workload-instance matching for better performance and savings.

CMP343 | Select and launch the right instance for your workload and budget

Explore the newest EC2 instances featuring Intel Xeon Scalable (Granite Rapids), AMD EPYC (Turin), and AWS Graviton processors. Learn how to choose the optimal instance type for your workload and budget requirements.

CMP305 | Assembling the Complete AI Stack: Optimizing your AI hardware on AWS

Learn how to optimize your AI infrastructure on AWS: Choose the right processors, accelerators, storage, and pricing models for your workloads. Get practical guidance on GPU selection, vector databases, and building cost-effective, scalable AI platforms.

CMP332 | Mastering EC2 Image Builder: From basics to advanced techniques

Hands-on session: Build an automated image pipeline with AWS experts. Learn the basics and advanced features such as multi-account distribution and continuous integration/continuous development (CI/CD) integration in 60 minutes.

CMP331 | Managing Amazon EC2 capacity and availability

Learn how to optimize EC2 costs and capacity using different reservation models, such as On-Demand, Capacity Blocks for machine learning (ML), and capacity reservations, to improve efficiency and availability.

CMP330 | Use Auto Scaling to proactively scale and optimize EC2 workloads

Learn how to harness the latest features of EC2 Auto Scaling to optimize your cloud resources. This hands-on workshop covers predictive scaling, dynamic scaling, and warm pools to automatically manage capacity based on demand. This is perfect for those wanting to improve application availability while reducing costs. Bring your laptop for practical exercises.

Learn about AWS Compute innovations

AWS has invested years into designing custom silicon optimized for the cloud to deliver the best price performance for a wide range of applications and workloads using AWS services. Learn more about the AWS Nitro System, processors at AWS, and ML chips.

CMP316 | Deep Dive into the AWS Nitro System

Explore the architecture behind the groundbreaking AWS Nitro System: the custom hardware and security components driving modern EC2 instances. Learn how this innovative platform enables unprecedented compute, storage, and networking capabilities, and discover the latest advances making new cloud possibilities reality.

CMP307 | AWS Graviton: The best price performance for your AWS workloads

Explore how AWS Graviton processors deliver superior performance and energy efficiency in EC2. Learn optimization best practices, common use cases, and customer success stories to accelerate your AWS Graviton adoption journey.

CMP336 | Optimize network and Amazon EBS intensive workloads on Amazon EC2 instances

Discover how to maximize the EC2 network and Amazon Elastic Block Store (Amazon EBS)-optimized instances for high-performance workloads. Learn to use new AWS Graviton and Intel instances for security appliances, databases, and network-intensive applications. Get practical insights into the latest networking and storage technologies to optimize your EC2 workload performance.

CMP315 | Maximizing EC2 Local NVMe Storage: Enhanced NVMe Metrics and Kubernetes Integration

Learn to optimize data-intensive workloads using AWS Nitro SSDs. Explore new performance metrics (latency, IOPS, throughput) and best practices for monitoring and tuning application performance.

CMP407 | Innovating with AWS confidential computing: An integrated approach

Learn how AWS confidential computing (Nitro System, Enclaves, TPM) protects sensitive data during processing. Explore solutions for secure data handling across CPU, GPU, and AI workloads.

CMP302 | Accelerating engineering: Cross-industry HPC cloud transformations

Discover how AWS high performance computing (HPC) transformed engineering and product development across industries. Learn how customers used cloud HPC to revolutionize their design processes to reduce time-to-market and increase innovation efficiency. Observe how HPC instances, Elastic Fabric Adapter (EFA), Amazon FSx for Lustre, and AWS ParallelCluster accelerate global R&D innovation.

Optimize your compute costs

At AWS, we focus on delivering the best possible cost structure for our customers. Frugality is one of our founding leadership principles. Cost effective design continues to shape everything we do, from how we develop products to how we run our operations. Come learn new ways to optimize your compute costs through AWS services, tools, and optimization strategies in the following sessions:

CMP347 | The Frugal Architect in a chaotic world

Discover the practical implementation of Werner Vogels’ Frugal Architect principles through a hands-on exploration of AWS Graviton, EC2 Spot, Karpenter, and AI tools. Watch as we optimize a shopping cart using AI and flame graphs, demonstrating how to build efficient systems without compromising quality. Learn to combine Karpenter’s intelligent scaling, the performance benefits of AWS Graviton, and AI-driven analysis to create systems that are faster, leaner, and more cost-effective by design.

CMP349 | 5-Star customer service: Duolingo’s path to compute savings

Learn how Duolingo partnered with their AWS Technical Account Manager to transform their cloud spending. Discover their successful transition to AWS Graviton processors, from initial cost analysis through enterprise-wide implementation. Observe how the AWS customer-focused approach delivered significant savings and business value for Duolingo.

CMP337 | Optimizing EC2: Hands-on strategies for cost-effective performance

Get hands-on with advanced EC2 instance optimization in this technical workshop. Learn to analyze workloads, measure performance metrics, and master benchmarking tools through guided exercises. Walk away with practical strategies to choose and tune EC2 instances for your specific application needs. Perfect for architects and developers looking to maximize their AWS infrastructure performance.

CMP314 | Data-driven EC2 optimization: Efficiency, metrics, and sustainability

Join this chalk talk to discover how metric-driven decisions can transform your EC2 fleet optimization. Through real-world scenarios, learn to analyze workload data, choose optimal instance types, and fine-tune capacity for your specific needs. We explore practical approaches to balance cost, performance, and sustainability using AWS-native tools, providing you with actionable strategies that you can implement immediately.

CMP412 | EC2 Flex instances: Get the latest generation performance at lower costs

Explore how EC2 Flex instances deliver the latest generation performance at reduced costs. Learn about optimal workload types, architectural design, and implementation strategies. Discover practical approaches to adoption and performance monitoring to maximize your EC2 Flex instance benefits.

Maximize your workload’s performance

Your workload’s performance matters beyond just cost because it directly impacts the quality, efficiency, and effectiveness of your compute solution. It can significantly influence customer satisfaction, business growth, and overall productivity. Even if a cheaper option exists, a low-cost option with poor performance can lead to long-term financial losses due to issues such as lost customers, engineering rework, and negative reputation. We have several sessions that help you optimize your workload’s performance.

CMP333 | Maximizing EC2 performance: A hands-on guide to instance optimization

Live coding session: Learn to optimize EC2 performance using Amazon CloudWatch and APerf. Observe real-world examples of workload analysis and code optimization across different instance types and programming languages.

CMP351 | Building for efficiency and reliability with performance testing on AWS

Learn performance testing strategies on AWS to optimize costs, identify bottlenecks, and improve reliability. Discover how to measure system behavior under various loads to inform architecture and instance selection decisions.

CMP405 | Everything you’ve wanted to know about performance on EC2 instances

Explore compute optimization techniques in this code talk. Learn about memory topology, hardware counters, hyperthreading effects, and methods for accurate performance testing and latency optimization.

Customer experience and applications with AI and ML

ML has been evolving for decades and has an inflection point with generative AI applications capturing widespread attention and imagination. Learn about generative AI infrastructure at Amazon or get hands-on experience building ML applications through our ML focused sessions, such as the following:

CMP201 | Architecting solution patterns for GPU-accelerated HPC and AI/ML

Interactive discussion on GPU-accelerated HPC and AI/ML architecture. Explore EC2 GPU instance families, architectural tradeoffs , and cost optimization strategies. Share your challenges and learn how to build scalable GPU solutions on AWS.

CMP403 | Build, scale, and optimize agentic AI on CPUs with AWS Graviton

Hands-on workshop: Build cost-efficient AI applications on AWS Graviton. Deploy large language model (LLM) inference, multi-agent systems, and vector databases using Amazon Elastic Kubernetes Service (Amazon EKS) and Karpenter. Create a chat app showcasing the performance benefits of AWS Graviton.

CMP346 | Supercharge ML and inference on Apple Silicon with EC2 Mac

Learn to optimize ML workloads on EC2 Mac instances with Apple silicon. Explore Apple Neural Engine, Core ML, and efficient PyTorch/TensorFlow deployment for iOS and cloud ML applications.

CMP338 | Protect privacy in generative AI applications using AWS Confidential Computing

Build three secure generative AI applications while learning to protect sensitive data in prompts, augmented sources, and model weights. Practice implementing AWS Confidential Computing features in EC2 to mitigate common security threats. Get hands-on experience using both open source models and Amazon Bedrock to create privacy-first AI solutions.

CMP410 | Secure generative AI using trusted execution environments

Hands-on session: Build a secure AI environment using Nitro TPM-enabled EC2 instances. Deploy an LLM with cryptographic attestation and learn to protect sensitive data using trusted execution environments.

Accelerate your AWS Graviton adoption journey

The AWS Graviton Processors are custom designed server processors designed by AWS. They deliver the best price performance for your cloud workloads running in AWS and help you reduce your carbon footprint. Ready to realize up to 40% better price performance for your workloads? We have curated the following session to help you accelerate your AWS Graviton adoption:

CMP329 | Learnings from developers adopting AWS Graviton at scale

Learn how the custom-designed AWS Graviton processors deliver optimal price-performance across diverse workloads: from microservices to HPC. Engage with AWS experts to explore adoption strategies, best practices, and real customer success stories for scaling AWS Graviton in production.

CMP352 | Unlock cost efficiency with AWS Graviton Savings Dashboard

Discover how the enhanced AWS Graviton Savings Dashboard provides deeper analytics for workload modernization, enabling up to 40% better price performance. Learn to use advanced features for granular workload analysis and streamlined migration planning. This lightning talk shows you how to transform efficiency insights into actionable strategies for measurable cloud cost savings.

CMP326 | Java modernization and performance optimization GameDay

Hands-on workshop: Use Amazon Q Developer to modernize Java applications from v8 to v21. Practice automated code analysis, performance benchmarking, and cost optimization across different instances. Laptop needed.

CMP335 | Optimize .NET TCO with agentic AI powered AWS Transform and AWS Graviton

Hands-on workshop: Use agentic AI to accelerate the migration of Windows-based .NET applications to .NET Core running on Linux with AWS Graviton for 40% better price performance. Learn code analysis, automated transformations, and CI/CD updates. For .NET developers/architects. Laptop needed.

Optimizing your container-based workloads

Maximizing the efficiency of container-based workloads is crucial for modern cloud applications. Whether you’re running microservices, web applications, or high-performance computing tasks, optimizing your container infrastructure can significantly impact both performance and cost. In this track, we’ve assembled essential sessions focused on using AWS Graviton processors and modernization tools to enhance your containerized applications. From real-world adoption stories to hands-on workshops, these sessions can help you achieve better price performance while maintaining operational excellence. Join us to explore the following:

CMP310 | Boost Amazon EKS efficiency: Amazon EKS Auto Mode, AWS Graviton, and EC2 Spot

Explore how Amazon EKS Auto Mode streamlines Kubernetes operations by removing infrastructure management complexity. Learn to optimize costs using AWS Graviton and EC2 Spot, with practical examples for building more efficient, cost-effective container environments.

CMP311 | Build once, run everywhere: Multi-architecture in your CI/CD pipelines

Learn to build multi-architecture containers for x86 and AWS Graviton processors. Observe how to optimize web applications for both platforms and integrate with CI/CD systems such as ArgoCD, GitLab, and GitHub.

CMP348 | Using Amazon Q to cost optimize your containerized workloads

Learn to achieve 40% better price-performance by migrating containerized workloads to AWS Graviton using Amazon EKS and Karpenter. Use Amazon Q to accelerate x86-to-Graviton migration, implement multi-architecture CI/CD pipelines, and optimize deployment strategies.

Quantum computing

Quantum computing is moving from theoretical possibility to practical reality, offering groundbreaking potential across industries. As organizations prepare for this technology, AWS provides the tools and infrastructure needed to explore quantum applications today. Through Amazon Braket, our managed quantum computing service, we’re making quantum experimentation accessible to enterprises, researchers, and developers alike. Whether you’re interested in drug discovery, optimization problems, or cybersecurity, this track offers a comprehensive journey from quantum basics to advanced hybrid solutions. Join industry leaders, such as AstraZeneca and Accenture, to discover how quantum computing is already delivering value and how you can begin your quantum journey:

CMP202 | Amazon Braket: Get hands-on with quantum computing

Get started with quantum computing in this practical workshop. Learn to implement quantum algorithms and run circuits on gate-based devices using Amazon Braket. Explore the quantum algorithm library of AWS through hands-on exercises. Bring your laptop to begin your quantum journey.

CMP209 | Amazon Braket hubs: Accelerating R&D in national quantum initiatives

Learn how AWS supports quantum computing research hubs worldwide, helping create secure environments and providing access to cutting-edge quantum technologies for researchers and startups.

CMP411 | Quantum computing with Amazon Braket: From exploration to enterprise

Explore quantum computing with Amazon Braket, featuring the AWS strategy and AstraZeneca’s drug discovery research. Learn how to combine quantum and classical workloads and prepare for future quantum technologies.

CMP205 | Q-CTRL Fire Opal on Amazon Braket: Quantum solutions from security to finance

Learn how organizations use Q-CTRL and Amazon Braket for quantum computing breakthroughs. Observe how Accenture Federal Services achieved 3x better network security detection using Q-CTRL’s optimizer, and explore quantum-classical solutions for various industries.

CMP304 | Architectures for hybrid quantum-classical workflows at scale

Learn to build hybrid quantum-classical computing solutions using Amazon Braket with AWS services (AWS Batch, AWS ParallelCluster) and GPU-accelerated instances. Explore architectures integrating CPUs, GPUs, and quantum processors using NVIDIA CUDA-Q.

Check out workload-specific sessions

EC2 offers the broadest and deepest compute platform to help you best match the needs of your workload. Join sessions focused on your specific workload to learn about how you can use AWS solutions to accelerate your innovations.

CMP207 | Startup to scale: Powering business growth with Amazon Lightsail

Get started in the cloud with just a few clicks with Amazon Lightsail. Discover how it can support your business at any stage of growth. Whether you’re launching your first cloud workload, migrating existing applications, or managing services for your customers, learn proven approaches for success. We explore how customers are using Lightsail today, including cost optimization and best practices for efficient scaling.

CMP320 | Full stack web apps on EC2: Using AWS Elastic Beanstalk with Amazon Q

Accelerate your cloud journey with AWS Elastic Beanstalk and Amazon Q. Learn how Elastic Beanstalk streamlines deployment and maintenance of full stack web applications on EC2 with automated infrastructure provisioning, while Amazon Q enhances your Elastic Beanstalk experience with natural language commands, intelligent troubleshooting guidance, and deployment best practices recommendations. This is perfect for teams ready to focus on building exceptional applications instead of managing infrastructure.

CMP334 | Modernize Apple platform development with AWS and EC2 Mac

Explore how EC2 Mac instances enable scalable, cost-effective macOS workloads on AWS. Learn about the latest features and hear a customer success story showcasing optimized Apple development workflows in the cloud.

CMP341 | SAP workloads on memory optimized Amazon EC2 instances

Discover how the memory-optimized instances (R, X, U) of EC2 revolutionize SAP HANA deployments, eliminating traditional infrastructure compromises. Learn from SAP’s experience managing RISE with SAP on AWS, and explore how high-memory instances can transform your SAP operations.

CMP319 | Exploring the spectrum of architecture patterns for 3D rendering

Explore the complete rendering toolkit of AWS for 3D and spatial applications: from GPU-powered EC2 instances to distributed rendering with Deadline Cloud and real-time GameLift Streams. Learn practical architecture patterns and cost optimization strategies to scale your rendering pipeline for games, architectural visualization, and AR/VR experiences.

CMP321 | Generative AI storyboarding: From Sketch to 3D Scene with generative AI on AWS

Learn to create visual content using Amazon Bedrock: convert sketches to storyboards, generate 2D/3D assets, and compose scenes. Explore AI-assisted workflows for film, games, and UI design while maintaining artistic control.

CMP211 | Hybrid science: AI + physics simulations for climate and life sciences

Explore how to combine AI with physics simulations using AWS services (such as AWS Batch, AWS ParallelCluster, Amazon FSx, EFA). Learn real-world patterns for integrating AI and simulation workflows in climate, weather, and healthcare applications.

CMP345 | Accelerate drug discovery R&D at scale with AWS

Interactive session on how top pharma companies use AWS for drug discovery R&D. Explore solutions for imaging, molecular simulation, and AI-driven research, with focus on managing large-scale data and diverse compute needs.

CMP350 | Accelerating vehicle innovation: ML and HPC best practices

Learn how Toyota and Deloitte transformed automotive engineering by migrating HPC and ML workloads to AWS. Using NVIDIA GPUs and EC2 HPC instances, they dramatically reduced development cycles. You can gain practical insights for your own high-performance computing initiatives.

CMP401 | Accelerating semiconductor design, simulation, and verification on AWS

This session covers the latest compute and storage innovations such as the new generation of EC2 instances powered by custom Intel Xeon Scalable processors (Granite Rapids), AMD EPYC processors (Turin), and AWS Graviton, and new features of Amazon FSx for NetApp ONTAP.

CMP406 | HPC infrastructure for financial services using AWS Batch and AWS CDK

Hands-on session: Build HPC infrastructure using AWS Cloud Development Kit (AWS CDK). Deploy AWS Batch for financial risk analysis workloads. This is suitable for HPC experts new to AWS and AWS developers new to HPC.

CMP204 | Quantum computing: Accelerating pharma innovation

Explore how Merck Sharp & Dohme partners with MathWorks and AWS to revolutionize pharmaceutical development through quantum computing. Using MATLAB and Amazon Braket, they implement QAOA for optimizing drug production and enhancing cancer diagnostics.

Ready to unlock new possibilities?

The AWS Compute team looks forward to seeing you in Las Vegas. Come meet us at the Compute Booth in the Expo and check out our various EC2 demos. And if you’re looking for more session recommendations, check-out more re:Invent attendee guides curated by experts.
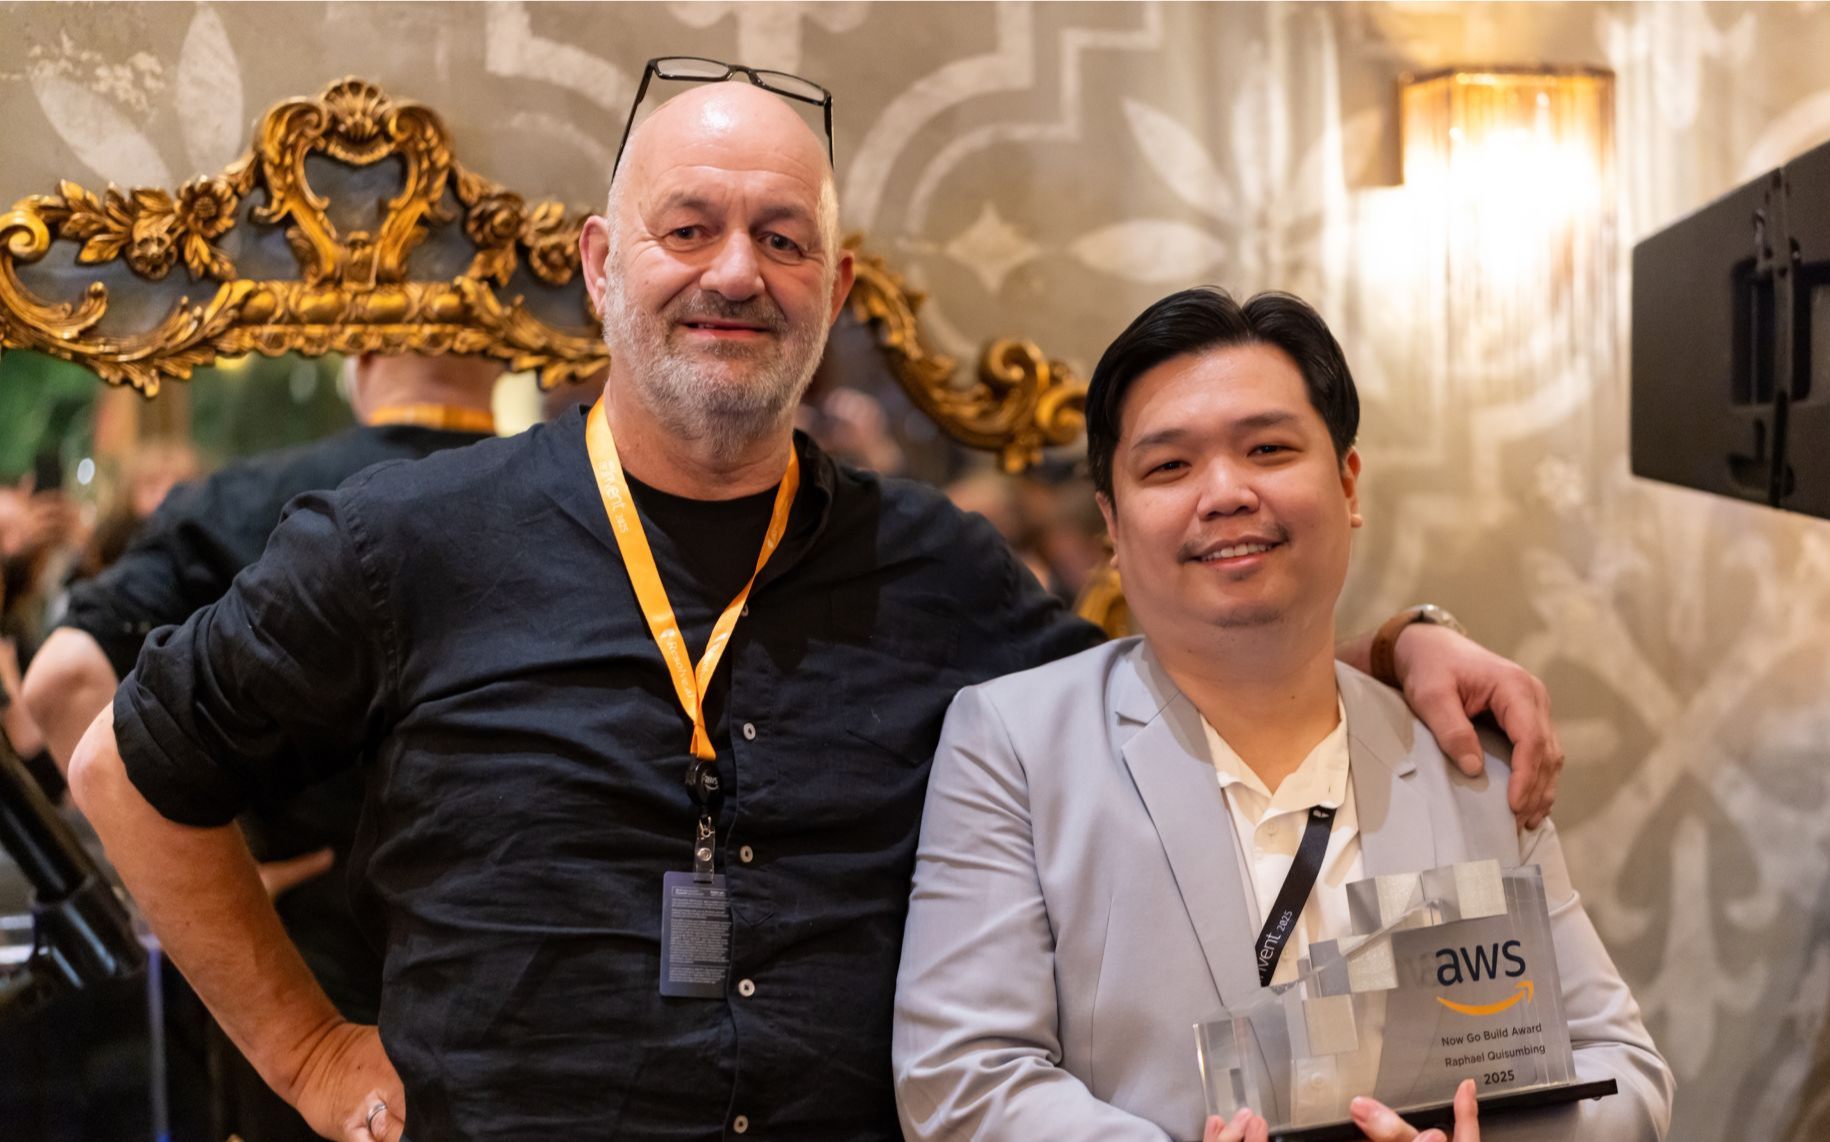
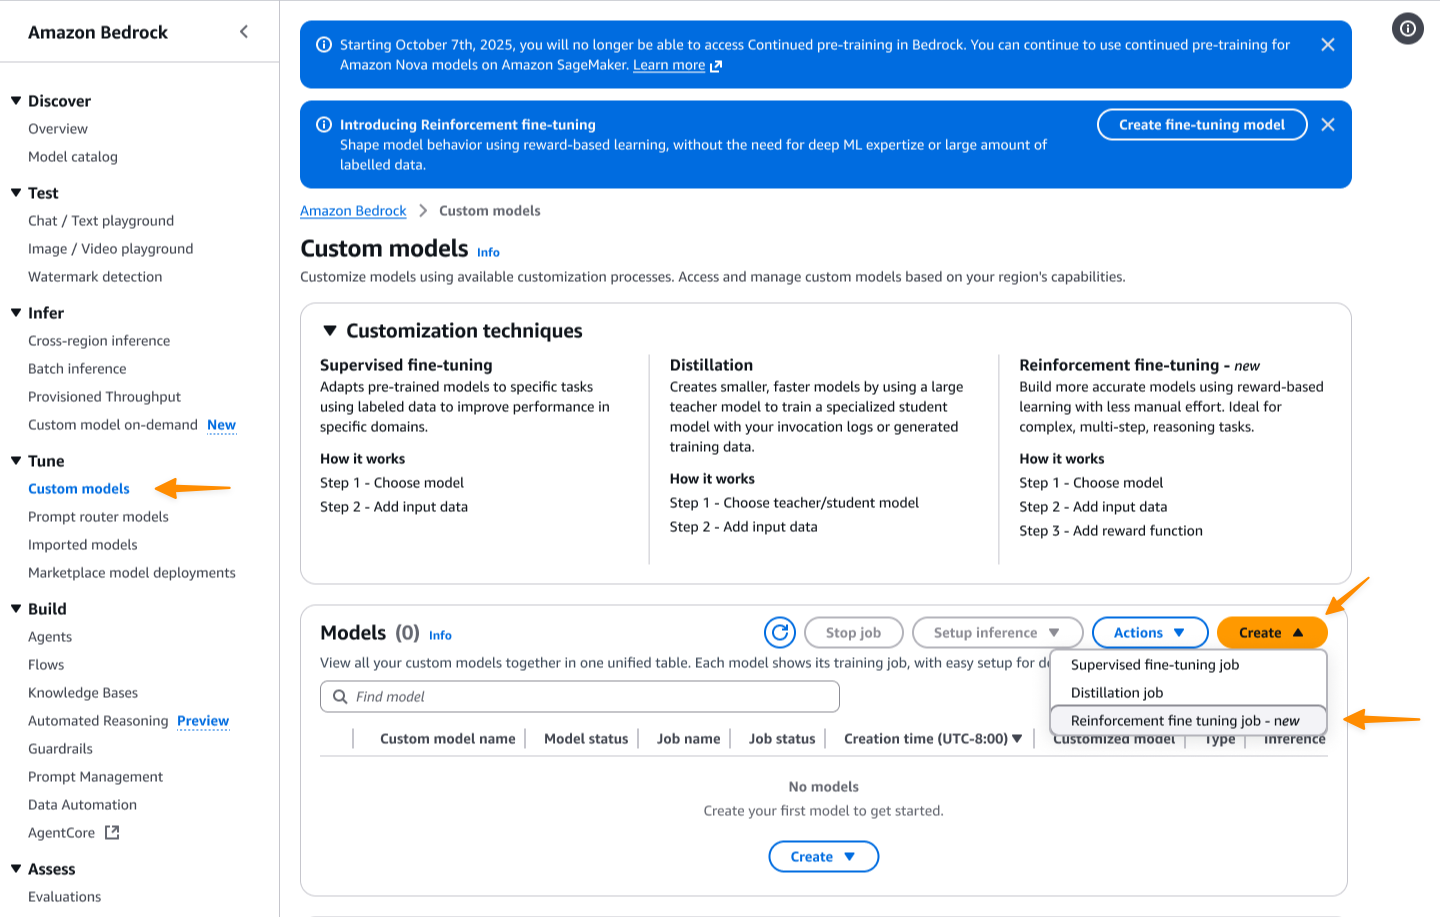
Enhance event experiences with a generative AI-powered WhatsApp assistant using AWS End User Messaging

Post Syndicated from Richard Perez original https://aws.amazon.com/blogs/messaging-and-targeting/enhance-event-experiences-with-a-generative-ai-powered-whatsapp-assistant-using-aws-end-user-messaging/

Technology conferences and events serve as vital opportunities for innovation, knowledge sharing, and networking in the rapidly evolving technology industry. These gatherings range from large international conventions attracting tens of thousands of attendees, or more specialized conferences focused on specific sectors such as AI, cybersecurity, or a particular industry.

In this post, we share how the AWS Communication Developer Services (CDS) team integrated an AWS End User Messaging Social WhatsApp channel with Amazon Bedrock to launch the AWS Summit Assistant Bot at the AWS Dubai Summit 2025, enhancing the experience of attendees in real-world applications.

AWS Global Summits

AWS Global Summits have become an important event in the technology community, offering invaluable opportunities for professionals to explore the latest cloud computing innovations and best practices. These summits, held in major cities worldwide, bring together developers, engineers, and business leaders to share knowledge, network, and gain hands-on experience with AWS technologies. The events typically feature keynote speeches from AWS executives and industry leaders, providing insights into future trends and strategic directions in cloud computing. Attendees can participate in technical sessions, workshops, and demos that cover a wide range of topics, from artificial intelligence and machine learning (AI/ML) to serverless computing. The impact of these summits extends beyond the events themselves, fostering a global community of cloud practitioners and driving innovation across various industries that rely on cloud technologies.

Attendee experience

Despite the valuable experience these events create, attendees often find navigating their way around these events challenging. Participants frequently find themselves uncertain about which sessions align best with their interests and expertise levels. Locating specific sessions within the venue can be time-consuming, and finding essential venue-specific areas such as quiet rooms or lost property offices has been a persistent pain point.

Users are increasingly reluctant to download single-use mobile apps due to friction like account creation, logins, storage, and app fatigue. Storyly notes that users spend 80% of their app time in their top three apps, with most others abandoned quickly. For event apps specifically, this reluctance stems from the same factors: app fatigue, privacy concerns about sharing personal information, and the time and effort required to set up and navigate yet another platform. Unless the value is immediate and clear, many attendees simply opt out, mirroring the broader trend where users avoid the hassle of downloading apps unless they offer sustained, high-value utility.

These challenges can detract from the overall event experience and can lead to missed opportunities for learning and networking.

How we enhanced the attendee experience

The AWS Summit Assistant Bot, launched at the AWS Dubai Summit (May 2025), offered a seamless solution to these attendee challenges. Attendees simply scanned QR codes that were strategically placed throughout the venue to initiate a WhatsApp chat with the AI-powered assistant. This innovative assistant uses advanced natural language processing to understand attendees’ interests and provide tailored session recommendations. Moreover, it offered real-time guidance on session locations and can direct users to various venue-specific areas, providing a smooth and efficient summit experience.

Solution overview

Let’s examine how the AWS Summit Assistant Bot architecture enables seamless interaction between attendees and summit information systems. The AWS Summit Assistant Bot design allows for real-time processing of attendee messages and response generation using Amazon Bedrock Knowledge Bases for helpful and relevant answers. The following diagram illustrates how various AWS services work together to process attendee messages.

The architecture follows a modular pattern with four key components that enable efficient message processing and analytics capabilities:

  • Custom metrics – Custom Amazon CloudWatch WhatsApp metrics enable real-time monitoring of engagement events through Amazon Simple Notification Service (Amazon SNS) topic integration. These metrics track message delivery status and read receipts, providing crucial operational and performance insights.
  • Inbound message processing – This pipeline forms the core functionality, implementing message validation filters for length and message type constraints, managing session state, and handling audio transcription workflows. Validated messages are published to a dedicated SNS topic for downstream consumption.
  • Response generation – This component uses Amazon Bedrock Knowledge Bases for intelligent message handling, with architecture designed for flexible integration of alternative processing engines. Future iterations of the AWS Summit Assistant Bot will use the Strands Agents SDK and tools.
  • Questions categorization – This framework provides contextual analytics beyond standard CloudWatch and AWS Lambda insights. This component implements an Amazon DynamoDB based categorization system that works in conjunction with Amazon Bedrock to dynamically classify and track inquiry patterns while maintaining user privacy through personally identifiable information (PII)-free analytics.

Technical implementation

Our serverless, event-driven architecture efficiently handles WhatsApp message processing through a seamless multi-stage workflow. When a WhatsApp message arrives, AWS End User Messaging receives it and immediately publishes it to an SNS topic. From there, the messages are written to Amazon Simple Queue Service (Amazon SQS) queues, which enables controlled and systematic processing. Lambda functions then handle the core business logic, processing these messages and managing interactions with DynamoDB. To generate responses, the system uses Amazon Bedrock Knowledge Bases to create personalized content for each user. Finally, these tailored responses are routed back to users through AWS End User Messaging, completing the WhatsApp communication cycle.

The system implements two parallel processes alongside the main message processing pipeline. The first is a categorization service that processes messages through Amazon SNS and Amazon SQS before using Lambda functions to analyze content against existing DynamoDB category records. This function either increments existing category counters or creates new categories as needed. The second parallel process handles custom CloudWatch metrics, following a similar initial flow through Amazon SNS and Amazon SQS, but employs specialized Lambda functions to extract and record engagement metrics for operational monitoring.

Generative AI integration

The Amazon Bedrock implementation encompasses two core AI capabilities:

  • A knowledge base retrieval system using OpenSearch vector embeddings and Anthropic’s Claude 3.7 Sonnet model for accurate information retrieval
  • A real-time message categorization engine that dynamically classifies incoming messages into existing categories or creates new ones based on content analysis

Voice message processing

The voice message handling system implements a sophisticated processing chain. WhatsApp voice messages in OGG format are processed through a Lambda based conversion pipeline using the ffmpeg library. The converted audio is then transcribed using Whisper through Amazon Bedrock Marketplace, chosen for its fast processing and robust multi-language support capabilities.

Security and privacy considerations

Our security-first approach implements multiple layers of protection:

  • Customer managed key encryption for data at rest and in transit across Amazon SNS, Amazon SQS, and DynamoDB
  • Minimized PII CloudWatch logging and automatic data cleanup through DynamoDB TTL settings
  • Amazon Bedrock Guardrails to prevent inappropriate content generation and protect against data loss
  • Custom logic to prevent resource draining by preventing the ingestion of unreasonably large messages and keeping a short conversation context window

Monitoring and analytics

Monitoring is important for operational purposes but also for understanding what questions users are asking. The solution uses the following components:

  • A Real-time CloudWatch dashboard for tracking operational metrics such as messages published on SNS topics; WhatsApp messages sent, delivered, and read, Lambda invocations; failures; and Amazon Bedrock metrics
  • CloudWatch logs for granular analytics using CloudWatch insights such as unique users and number of conversations
  • Generative AI-powered categorization of users’ questions

Conclusion

The AWS Summit Assistant Bot demonstrates how AWS services can be combined to create practical, generative AI-powered solutions that enhance real-world experiences. This framework can be adapted for various event types and scales, such as tech conferences, trade shows, festivals, campus orientations, and shopping centers.

To learn more about building similar solutions:

By using these AWS services and resources, you can create innovative, AI-powered communication solutions for a wide range of applications.


About the authors

AWS services scale to new heights for Prime Day 2025: key metrics and milestones

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-services-scale-to-new-heights-for-prime-day-2025-key-metrics-and-milestones/

Amazon Prime Day 2025 was the biggest Amazon Prime Day shopping event ever, setting records for both sales volume and total items sold during the 4-day event. Prime members saved billions while shopping Amazon’s millions of deals during the event.

This year marked a significant transformation in the Prime Day experience through advancements in the generative AI offerings from Amazon and AWS. Customers used Alexa+—the Amazon next-generation personal assistant now available in early access to millions of customers—along with the AI-powered shopping assistant, Rufus, and AI Shopping Guides. These features, built on more than 15 years of cloud innovation and machine learning expertise from AWS, combined with deep retail and consumer experience from Amazon, helped customers quickly discover deals and get product information, complementing the fast, free delivery that Prime members enjoy year-round.

As part of our annual tradition to tell you about how AWS powered Prime Day for record-breaking sales, I want to share the services and chart-topping metrics from AWS that made your amazing shopping experience possible.


Prime Day 2025 – all the numbers
During the weeks leading up to big shopping events like Prime Day, Amazon fulfillment centers and delivery stations work to get ready and ensure operations run efficiently and safely. For example, the Amazon automated storage and retrieval system (ASRS) operates a global fleet of industrial mobile robots that move goods around Amazon fulfillment centers.

AWS Outposts, a fully managed service that extends the AWS experience on-premises, powers software applications that manage the command-and-control of Amazon ASRS and supports same-day and next-day deliveries through low-latency processing of critical robotic commands.

During Prime Day 2025, AWS Outposts at one of the largest Amazon fulfillment centers sent more than 524 million commands to over 7,000 robots, reaching peak volumes of 8 million commands per hour—a 160 percent increase compared to Prime Day 2024.

Here are some more interesting, mind-blowing metrics:

  • Amazon Elastic Compute Cloud (Amazon EC2) – During Prime Day 2025, AWS Graviton, a family of processors designed to deliver the best price performance for cloud workloads running in Amazon EC2, powered more than 40 percent of the Amazon EC2 compute used by Amazon.com. Amazon also deployed over 87,000 AWS Inferentia and AWS Trainium chips – custom silicon chips for deep learning and generative AI training and inference – to power Amazon Rufus for Prime Day.
  • Amazon SageMaker AI — Amazon SageMaker AI, a fully managed service that brings together a broad set of tools to enable high-performance, low-cost machine learning (ML), processed more than 626 billion inference requests during Prime Day 2025.
  • Amazon Elastic Container Service (Amazon ECS) and AWS Fargate– Amazon Elastic Container Service (Amazon ECS) is a fully managed container orchestration service that works seamlessly with AWS Fargate, a serverless compute engine for containers. During Prime Day 2025, Amazon ECS launched an average of 18.4 million tasks per day on AWS Fargate, representing a 77 percent increase from the previous year’s Prime Day average.
  • AWS Fault Injection Service (AWS FIS) – We ran over 6,800 AWS FIS experiments—over eight times more than we conducted in 2024—to test resilience and ensure Amazon.com remains highly available on Prime Day. This significant increase was made possible by two improvements: new Amazon ECS support for network fault injection experiments on AWS Fargate, and the integration of FIS testing in continuous integration and continuous delivery (CI/CD) pipelines.
  • AWS Lambda – AWS Lambda, a serverless compute service that lets you run code without managing infrastructure, handled over 1.7 trillion invocations per day during Prime Day 2025.
  • Amazon API Gateway – During Prime Day 2025, Amazon API Gateway, a fully managed service that makes it easy to create, maintain, and secure APIs at any scale, processed over 1 trillion internal service requests—a 30 percent increase in requests on average per day compared to Prime Day 2024.
  • Amazon CloudFront – Amazon CloudFront, a content delivery network (CDN) service that securely delivers content with low latency and high transfer speeds, delivered over 3 trillion HTTP requests during the global week of Prime Day 2025, a 43 percent increase in requests compared to Prime Day 2024.
  • Amazon Elastic Block Store (Amazon EBS) – During Prime Day 2025, Amazon EBS, our high-performance block storage service, peaked at 20.3 trillion I/O operations, moving up to an exabyte of data daily.
  • Amazon Aurora – On Prime Day, Amazon Aurora, a relational database management system (RDBMS) built for high performance and availability at global scale for PostgreSQL, MySQL, and DSQL, processed 500 billion transactions, stored 4,071 terabytes of data, and transferred 999 terabytes of data.
  • Amazon DynamoDB – Amazon DynamoDB, a serverless, fully managed, distributed NoSQL database, powers multiple high-traffic Amazon properties and systems including Alexa, the Amazon.com sites, and all Amazon fulfillment centers. Over the course of Prime Day, these sources made tens of trillions of calls to the DynamoDB API. DynamoDB maintained high availability while delivering single-digit millisecond responses and peaking at 151 million requests per second.
  • Amazon ElastiCache – During Prime Day, Amazon ElastiCache, a fully managed caching service delivering microsecond latency, peaked at serving over 1.5 quadrillion daily requests and over 1.4 trillion requests in a minute.
  • Amazon Kinesis Data Streams – Amazon Kinesis Data Streams, a fully managed serverless data streaming service, processed a peak of 807 million records per second during Prime Day 2025.
  • Amazon Simple Queue Service (Amazon SQS) – During Prime Day 2025, Amazon SQS – a fully managed message queuing service for microservices, distributed systems, and serverless applications – set a new peak traffic record of 166 million messages per second.
  • Amazon GuardDuty – During Prime Day 2025, Amazon GuardDuty, an intelligent threat detection service, monitored an average of 8.9 trillion log events per hour, a 48.9 percent increase from last year’s Prime Day.
  • AWS CloudTrail – AWS CloudTrail, which tracks user activity and API usage on AWS, as well as in hybrid and multicloud environments, processed over 2.5 trillion events during Prime Day 2025, compared to 976 billion events in 2024.

Prepare to scale
If you’re preparing for similar business-critical events, product launches, and migrations, I recommend that you take advantage of our newly branded AWS Countdown (formerly known as AWS Infrastructure Event Management, or IEM). This comprehensive support program helps assess operational readiness, identify and mitigate risks, and plan capacity, using proven playbooks developed by AWS experts. We’ve expanded to include: generative AI implementation support to help you confidently launch and scale AI initiatives; migration and modernization support, including mainframe modernization; and infrastructure optimization for specialized sectors including election systems, retail operations, healthcare services, and sports and gaming events.
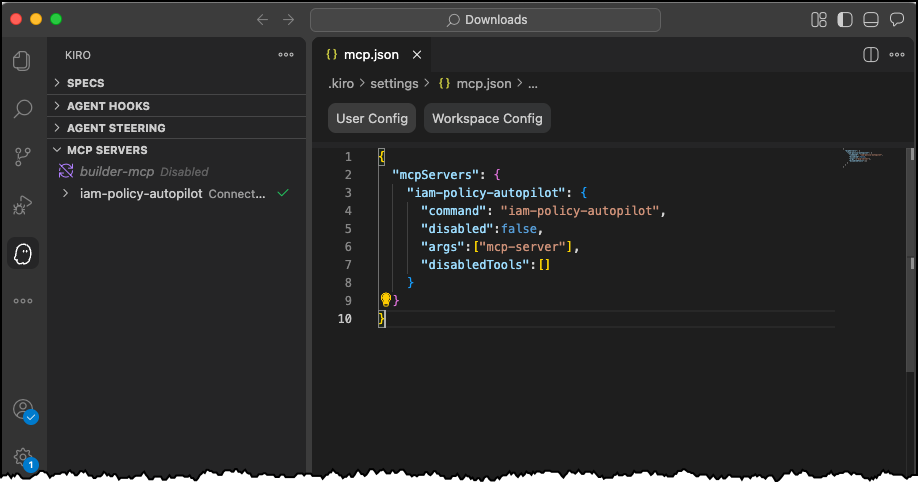
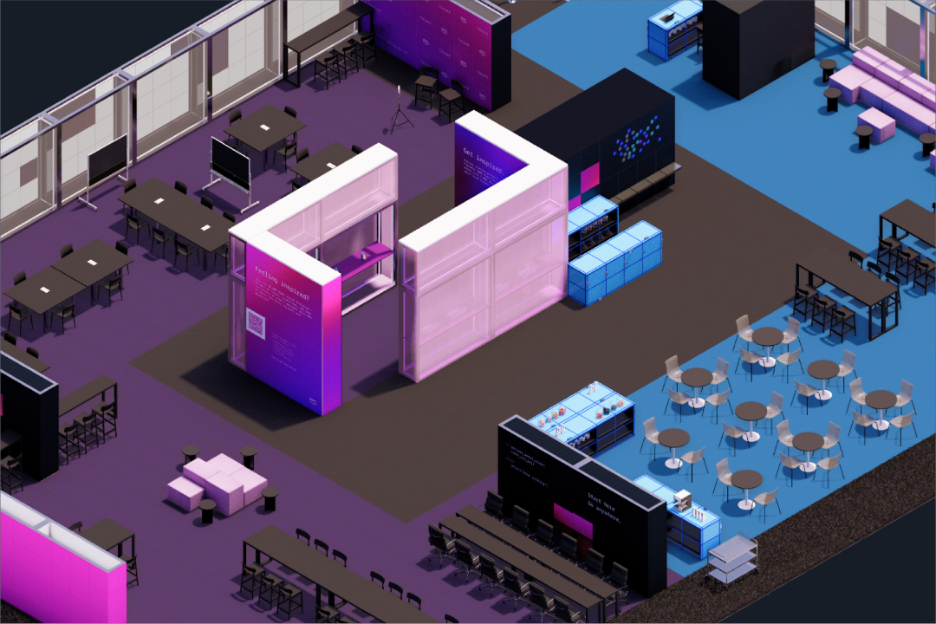
I look forward to seeing what other records will be broken next year!

Channy

How UP Tombou Digitally Transformed with Nebosystems (Presented at InfoSec SEE 2025)

Post Syndicated from Dora original https://nebosystems.eu/how-up-tombou-digitally-transformed-with-nebosystems/

About UP Tombou

UP Tombou is one of Bulgaria’s leading providers of food vouchers, gift cards and employee benefit solutions, serving thousands of businesses nationwide for over 30 years.
But despite their strong market presence, Tombou’s internal IT infrastructure was holding them back.
The Challenge: Legacy Systems and Poor IT Support

Prior to partnering with Nebosystems, Tombou faced serious IT hurdles:

  • Outdated and fragmented infrastructure
  • Inconsistent and slow internal IT support
  • Missed deadlines and operational delays
  • Poorly maintained documentation and weak security practices
  • No disaster recovery or business continuity strategy

These weaknesses posed serious risks — both to operations and compliance.

The Turning Point: Partnering with Nebosystems

In early 2024, Tombou signed a long-term contract with Nebosystems to fully manage and modernize their IT environment. The goal: build a secure, scalable and compliant digital infrastructure to support their expanding operations.

Infrastructure Modernization

Nebosystems began with a foundational rebuild:

  • Proxmox host cluster for virtualization and high availability
  • Enterprise-grade IBM storage systems
  • Local and offsite backup systems with automated disaster recovery
  • Regular disaster recovery testing to validate data integrity and recovery speed
  • Implementation of an ISO 27001-compliant Business Continuity Plan (BCP)
  • Modernized network with MikroTik routers, managed switches, and a Next-Gen Firewall

This laid the groundwork for operational resilience and compliance.

Endpoint Security with Bitdefender EDR

Security was a key priority. Bitdefender EDR was deployed across all Windows endpoints, enabling:

  • Real-time threat detection and prevention
  • Centralized policy control for compliance and auditing
  • Defense against ransomware, zero-days, and targeted attacks
  • Automatic alerting to security incidents

This fulfilled essential ISO 27001 requirements while raising the security baseline across the company.

Full Audit & Control with Netwrix

Visibility is everything in modern IT — and UP Tombou now has it. Netwrix Auditor was implemented to:

  • Track all changes in Active Directory
  • Monitor file access and modifications on Windows file servers
  • Deliver real-time alerts on high-risk actions (e.g., mass file deletions)
  • Provide daily reports to ensure proactive oversight and accountability

With Netwrix, Tombou now has a transparent and audit-ready IT environment.

Office 365 Migration & Unified Communication

The internal mail server was successfully migrated to Microsoft 365, improving communication, reliability and integration. A modern virtual phone system was also deployed to replace outdated telephony infrastructure.

24/7 Monitoring and Centralized IT Task Management

To maximize uptime and response speed, Nebosystems deployed:

  • Around-the-clock infrastructure monitoring
  • Automated alerts for hardware and disk issues
  • A centralized ticketing system for efficient IT task management and issue resolution

This success story was featured live at InfoSec SEE 2025, Southeastern Europe’s leading cybersecurity conference. Representatives from Nebosystems and UP Tombou shared the transformation journey with IT leaders and compliance experts from across the region.

InfoSec SEE 2025 Recognition – Netwrix Partner of the Year

Thanks to successful digital transformation projects like this one, Nebosystems was named:

Netwrix Partner of the Year 2025
This recognition affirms Nebosystems’ commitment to high-impact solutions and long-term client success.

The Results

  • Secure, high-availability IT systems
  • Full ISO 27001 technical alignment
  • Increased productivity and zero unplanned downtime
  • Regular backup validation and disaster recovery testing
  • Streamlined IT operations through a professional ticketing system
  • Ongoing partnership built on trust and performance

Ready to Transform Your IT?

If your business is struggling with outdated infrastructure, security concerns or compliance pressure — Nebosystems can help.

Get in touch to learn how we can build a modern, secure, and audit-ready IT environment tailored to your needs.

AI security strategies from Amazon and the CIA: Insights from AWS Summit Washington, DC

Post Syndicated from Danielle Ruderman original https://aws.amazon.com/blogs/security/ai-security-strategies-from-amazon-and-the-cia-insights-from-aws-summit-washington-dc/

Speakers during AWS Summit Washington, DC 2025 on June 10, 2025.

At this year’s AWS Summit in Washington, DC, I had the privilege of moderating a fireside chat with Steve Schmidt, Amazon’s Chief Security Officer, and Lakshmi Raman, the CIA’s Chief Artificial Intelligence Officer. Our discussion explored how AI is transforming cybersecurity, threat response, and innovation across the public and private sectors. The conversation highlighted several key themes: how organizations can leverage AI to improve security outcomes, the rise of agentic AI and its impact on security, the importance of maintaining human oversight in AI systems, workforce development strategies, and practical approaches to implementing AI securely in enterprise environments. Below are a few excerpts from our conversation.

On leveraging AI to improve security outcomes

Steve Schmidt: “We’ve applied AI internally at Amazon in a couple of places that led to some significant benefits, including in the application security review process. By training our large language models internally on prior security reviews that we’ve done, it has allowed us to apply the knowledge and learning that our more senior staff have embodied in the documents that the LLM was trained on and expose that to our more junior staff. It really raises the bar on the absolute level of security that we can offer.”

Lakshmi Raman: “In the cybersecurity realm, we’re thinking about how AI helps us in our accreditation and authorization process, helping us ensure that the process to get systems accredited is going as quickly as possible, because the industry is moving so fast. Another area that we’re applying AI and machine learning is triaging data. We have vast amounts of data that comes in at an exponential rate, so we need to be able to go through it quickly so that we can surface insights. You can imagine a cybersecurity analyst who traditionally has gone through network data manually in order to think about blocking suspicious IP addresses or connections. Now there’s an opportunity to do all of that really efficiently and let the security analysts make the decision.”

On the rise of agentic AI and its implications for security

Steve Schmidt: “The biggest change we’re seeing right now in AI is the rise of agentic AI. The reason agentic AI is particularly interesting is that it brings with it a set of challenges about ensuring the software is taking actions within the context of the person who’s asking it…Think about that in the context of a government organization, where you have sets of information that are restricted to certain populations, there are classification decisions, access control limitations, and reasons that you can access certain data that have to be present before you can do so. Agentic AI brings opportunities—you can take actions using software automatically—but also challenges: how do we make sure that the software is doing exactly the right thing every single time, and more importantly, that we can prove what it did to stakeholders and regulators?”

Lakshmi Raman: “AI agents definitely have an opportunity to transform enterprise automation. Leveraging them to do complex multi-step workflows—to do tool calling across a variety of databases and other foundational tools—has tremendous potential, with a human as a crucial step to review what’s going on.”

On the importance of maintaining human oversight with AI

Lakshmi Raman: “In my world, I spend a lot of time thinking about how AI is impacting the workforce. One of the areas we’re looking at is the intersection between AI and our people. AI is able to speed up the processing and do automation, but at the end of the day, it’s really about who is taking on the risk, or deciding the intents and making the decisions. Whatever the machine output happens to be, really it’s about the human who’s deciding the level of oversight, the risk to take, and even whether to intervene.”

Steve Schmidt: “One thing that many people don’t realize about AI systems is that they’re nondeterministic. What nondeterminism means is you can ask an AI model the same question 100 times, and you will not get the same answer every time. So, having a human who can make a judgment about what the AI comes up with is critically important. We look at it this way: if you’re just asking a question and getting an answer, that may be one set of scrutiny that you have to get assistance. But if you’re going to take an action, you’ve got to be really sure the AI is correct. There has to be that skilled person that Lakshmi spoke about, at the end of the AI use process saying, ‘Yes, this is the right thing to do at this point in time with this context.’”

On building an AI-savvy security workforce

Steve Schmidt: “There’s a real problem in our industry: we don’t have enough security people. We simply can’t hire enough people with the right skills to do this job. What we’ve we found is that AI allows us to do a lot of the heavy lifting for the security staff, using tooling that used to have to be done by humans. Our staff is actually materially happier with their jobs if we remove a lot of that grunt work from them, which is super important. You want to keep the employees you have, so you give them tooling that helps them get the job done more efficiently, and they enjoy their job.”

Lakshmi Raman: “We’re looking for people who can live between the intersection of technology and social intelligence, people who can understand how those two areas can potentially interact around human behavior and how to think about future activities. When we’re thinking about analysts, for example, we’re thinking about people who have critical thinking skills, who can demonstrate analytic rigor, who can think multiple steps ahead with incomplete information. We’re also looking for people who have digital acumen with an understanding of cloud and cyber and AI, so that we have those technical skills in house. And finally, people who are interested in lifelong learning and curiosity, because threats change over the years. We need people who understand and are willing to learn about that.”

On advice for security leaders as AI accelerates

Steve Schmidt: “When you’re looking at making a decision, ask the person who’s bringing the information to you: ‘Why can’t AI do this?’ And if they don’t have an answer, ask ‘When will it be able to and under what condition?’ Move it into the now, the probable, the possible, and make it real for all of your staff all the time. If they’re not intentionally making that decision, they’re missing an opportunity.”

Lakshmi Raman: “You’ve got to get training out there for your users. We think of it at three different levels. First is our general workforce—which might be the most important user base—people who are sitting side by side with our AI practitioners and can help describe the workflows that need automation. Then we think about it for our practitioners, so they are keeping up with the latest. And then finally, our senior executives, who can think about how they can transform their organization with AI and generate that buy-in from the top level.”

AI is not just changing what we can do, but how we work. As Steve and Lakshmi emphasized, the most successful AI implementations will be those that thoughtfully balance automation with human oversight, focusing on use cases that deliver tangible value while managing risks appropriately. For security professionals, understanding both the technical and human dimensions of AI will be critical as we navigate this changing space.

Danielle Ruderman

Danielle Ruderman

Danielle is a Senior Manager for the AWS Worldwide Security Specialist Organization, where she leads a team that enables global CISOs and security leaders to better secure their cloud environments. Danielle is passionate about improving security by building company security culture that starts with employee engagement.