Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=FuTEz_VGiBg
Dr. Robert Wachter | A Giant Leap: How AI Is Transforming Healthcare… | Talks at Google
Post Syndicated from Talks at Google original https://www.youtube.com/watch?v=zKMWLs3S9yg
Authenticate legitimate AI agent traffic with AWS WAF Bot Control
Post Syndicated from Harith Gaddamanugu original https://aws.amazon.com/blogs/security/authenticate-legitimate-ai-agent-traffic-with-aws-waf-bot-control/
As AI agents and automated tools increasingly access web applications, distinguishing legitimate bot traffic from malicious attempts has become a critical security challenge. Traditional approaches such as IP-based filtering and reverse DNS lookups fail in multi-tenant systems (such as Amazon Bedrock AgentCore) where thousands of distinct workloads share the same IP space. Attackers can easily spoof user agents, and manual allowlists don’t scale with growing demand.
Web Bot Authentication (WBA), available in AWS WAF Bot Control since November 2025, solves this challenge by implementing cryptographic signatures that provide tamper-proof verification of bot identities. WBA uses asymmetric cryptography to verify that a request comes from an authorized automated agent, relying on two active Internet Engineering Task Force (IETF) drafts: a directory draft for sharing public keys, and a protocol draft defining how keys attach crawler identity to HTTP requests.
With WBA, you can confidently identify trusted automated access while maintaining granular control through WAF labels, creating a more secure and manageable ecosystem for both bot operators and website owners. AWS WAF Bot Control respects WBA verification status by default, automatically allowing verified AI agent traffic.
This post provides a deeper technical guide to implementing WBA with AWS WAF. You learn how WBA works, explore the new labels and capabilities it introduces, and walk through a step-by-step implementation—including signing code—to authenticate bot traffic using cryptographic signatures.
How Web Bot Authentication works with AWS WAF
WBA uses asymmetric cryptography to verify bot identities through HTTP message signatures. The process works as follows:
- Bot registration – Bot operators publish their public keys in a signature directory. AWS WAF regularly polls these directories and maintains a valid key registry.
- Request signing – Each bot operator’s request is signed using their private key following the IETF standard HTTP Message Signatures (RFC 9421).
- Verification – AWS WAF verifies signatures against known public keys associated with the bot operator and appends labels related to verification status.
A typical WBA-signed request includes headers like the following:
The following sequence diagram shows how AWS WAF verifies bot signatures and applies labels for allow or block decisions.
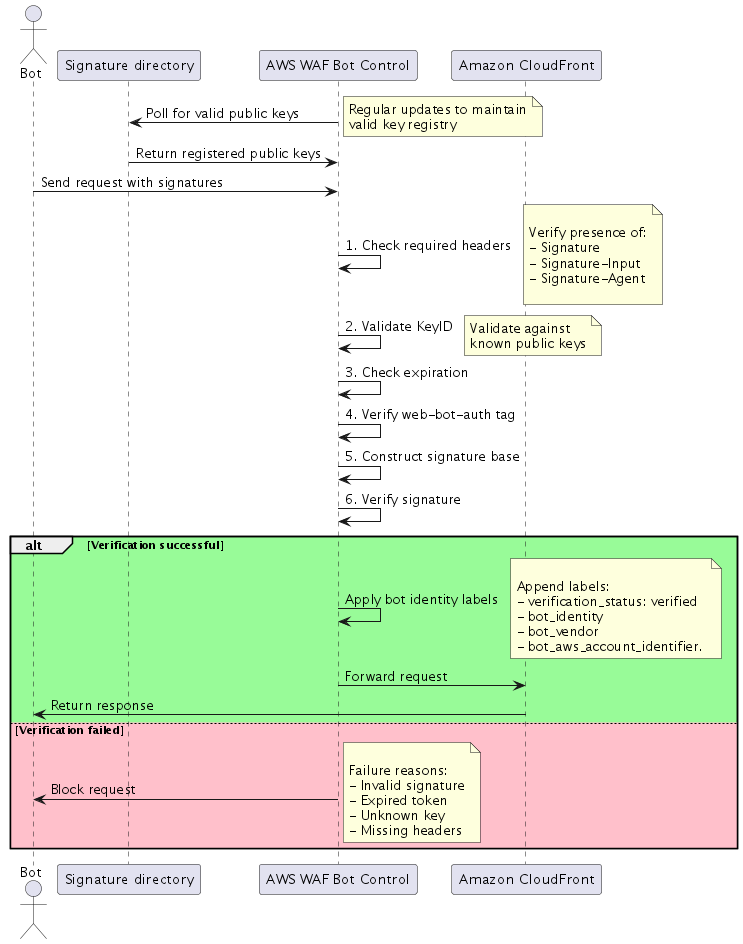
Figure 1 – AWS WAF Web Bot Authentication verification flow
The workflow shown in figure 1 includes the following steps:
- A bot sends a signed request to Amazon CloudFront and is inspected by AWS WAF Bot Control
- AWS WAF Bot Control retrieves the bot operator’s public key from the signature directory
- AWS WAF Bot Control verifies the ed25519 signature
- AWS WAF Bot Control appends a verification label (
verified,invalid,expired, orunknown_bot)
AWS WAF Bot Control evaluates rules using the label to allow or block the request.
New capabilities added to AWS WAF
With the addition of WBA, the following capabilities were added to AWS WAF.
Cryptographic bot verification
When a bot sends a request, it includes HTTP message signatures that AWS WAF validates at the edge using the AWS WAF Bot Control rule group (version 4.0 and later). This validation process adds minimal latency to requests while providing cryptographic certainty about the bot’s identity. HTTP Message Signatures is an open IETF standard (RFC 9421) that defines a mechanism for signing and verifying HTTP messages using asymmetric keys—in practice, this means a bot cryptographically signs specific headers and metadata of each request, and the receiver can verify the signature using the bot’s published public key.
New labels within AWS WAF for granular control
AWS WAF automatically validates signatures, and successfully validated traffic is immediately marked as verified. This verification status can be used in WAF rules and bot management policies, giving you the ability to write your own rules based on the new functionality.
The following table describes the new labels.
| Label | Meaning | Suggested action |
| awswaf:managed:aws:bot-control:bot:web_bot_auth:verified | Successful cryptographic verification | Allow |
| awswaf:managed:aws:bot-control:bot:web_bot_auth:invalid | Failed verification attempt | Block or rate-limit |
| awswaf:managed:aws:bot-control:bot:web_bot_auth:expired | Expired key used | Block and alert |
| awswaf:managed:aws:bot-control:bot:web_bot_auth:unknown_bot | Unrecognized key | Monitor or block |
| awswaf:managed:aws:bot-control:bot:vendor:<vendor_name> | Bot vendor or operator | Use for vendor-specific rules |
| awswaf:managed:aws:bot-control:bot:name:<rfc_name> | Bot name (RFC token from WBA) | Use for bot-specific rules |
| awswaf:managed:aws:bot-control:bot:account:<hash> | AWS account identifier (Amazon Bedrock AgentCore agents only) | Use for account-level controls |
AWS WAF now automatically allows verified AI agent traffic
AWS WAF Bot Control now respects WBA verification status by default, automatically allowing verified AI agent traffic. This includes two specific behavior changes:
- Category:AI rule update – Previously, the
Category:AIrule under common Bot Control blocked unverified bots. Bot Control now checks WBA verification status before applying this rule. - TGT_TokenAbsent rule update – The
TGT_TokenAbsentrule, which detects requests without a WAF token, no longer matches requests that carry theweb_bot_auth:verifiedlabel.
Key benefits for AWS WAF customers
WBA with AWS WAF delivers several advantages for organizations managing automated traffic at scale.
- Enhanced bot visibility – Clear identification of distinct bots operating from multi-tenant platforms like Amazon Bedrock AgentCore, providing transparency into automated traffic sources. The AWS WAF console includes a new AI activity dashboard that provides a centralized view of AI bot and agent traffic across your protected resources.
- Enhanced security – Cryptographic verification of bot identities using industry-standard signing mechanisms.
- Reduced false positives – Accurate distinction between legitimate and malicious automated traffic, particularly in shared IP environments.
- Industry alignment – Alignment with industry standards and major content delivery network (CDN) providers for consistent bot authentication across platforms.
Customer use cases for WBA with AWS WAF
Across industries, organizations use WBA to grant automated agents secure, controlled access to their web applications. The following scenarios highlight where this capability delivers real-world value:
- Verified customer support agents – Authenticate AI-powered chat and support bots so websites can recognize them as approved, registered agents. This enables seamless customer service automation while maintaining security controls and audit trails.
- Automated crawling and indexing – Allow search engine crawlers and content indexers to fetch pages with clear identity and scoped permissions. This reduces false-positive blocks, improves crawl efficiency, and helps legitimate bots access your content without triggering security controls.
- Partner integrations – Third-party agents can access customer portals and APIs with explicit consent and granular, scoped access controls. This facilitates secure business-to-business (B2B) integrations while maintaining visibility into partner bot activity.
- Enterprise automations and agents – Internal automation tools—including monitoring systems, QA bots, continuous integration and delivery (CI/CD) pipelines, and robotic process automation (RPA) solutions—get authenticated access to web applications with least-privilege access principles and full auditability.
Availability
WBA was introduced in Bot Control rule group Version_4.0 (November 2025) for Amazon CloudFront distributions, with continued support in later versions. With Version_6.0, WBA is available for resource types supported by AWS WAF across standard commercial AWS Regions.
Getting started: Developers or agents quick start
Whether you’re implementing WBA yourself or working with an AI coding assistant, the following steps walk you through deploying WBA, signing requests, and writing custom rules.
Step 1: Deploy the WBA-enabled Bot Control
Add the AWS WAF Bot Control rule group to your CloudFront-associated web ACL using static Version_4.0 or Version_5.0—both include WBA support for cryptographic bot verification. Version_5.0 (released February 2026) covers more than 650 unique bots and agents spanning categories including AI search engine crawlers, AI data collectors, AI assistants, and large language model (LLM) training crawlers.
Important: You must explicitly select one of these static versions.
The following example CloudFormation YAML snippet shows a bot control rule set configuration:
Step 2: Sign requests from your bot
If your agent runs on Amazon Bedrock AgentCore Browser, request signing is handled automatically—no additional configuration is required.
For agents running outside of AgentCore, registration APIs are on the roadmap that you can use to sign requests independently by:
- Generating an ed25519 key pair
- Hosting your public key in a signature directory
- Signing outbound HTTP requests using the Signature-Input and Signature headers with the
web-bot-authtag. For language-specific signing implementations, see the HTTP Message Signatures RFC (RFC 9421) and the AWS WAF Bot Control documentation.
Step 3: Write custom rules using WBA labels
Use the verification labels in custom WAF rules for granular traffic control, for example:
- Allow –
awswaf:managed:aws:bot-control:bot:web_bot_auth:verified - Rate-limit –
awswaf:managed:aws:bot-control:bot:web_bot_auth:invalid - Alert on –
awswaf:managed:aws:bot-control:bot:web_bot_auth:expired
Step 4: Monitor WBA traffic
Use AWS WAF metrics and logs to monitor authenticated bot traffic:
- Review Amazon CloudWatch metrics for Bot Control rule group matches and set up alarms for anomalous or unexpected spikes in invalid or expired verification attempts.
- Analyze AWS WAF logs to identify patterns in bot authentication attempts and filter on
web_bot_authlabels. - Use the AI Activity Dashboard in the AWS WAF console for a centralized view of AI bot traffic. Visualize traffic trends, identify top bots and frequently targeted paths, and filter by verification status to decide which bots to allow, rate-limit, or block.
Conclusion
WBA with AWS WAF provides a cryptographically secure, standards-based approach to authenticating legitimate AI agent traffic. By moving from IP-based allowlisting to signature-based verification, you gain accurate bot identification that works across multi-tenant environments.
Looking ahead, our focus is to simplify bot authentication and make it safer by default. Registration APIs that agent owners can use to cryptographically verify bot identity and intent are on the roadmap, helping website owners quickly distinguish trusted automation from unknown traffic.
If you own an agent, adopt WBA and register your agent to receive verified status. In parallel, AWS continues to actively participate in the IETF web-bot-auth working group, advocating for complementary approaches—using both identifying and anonymous verification protocols—and will incorporate these standards into products as they mature to help your deployments stay aligned with the broader ecosystem.
To get started, see the AWS WAF Bot Control documentation and the HTTP Message Signatures RFC (RFC 9421).
If you have feedback about this post, submit comments in the Comments section below.
Запазените паркоместа в София – нови данни
Post Syndicated from Боян Юруков original https://yurukov.net/blog/2026/slujebno2/
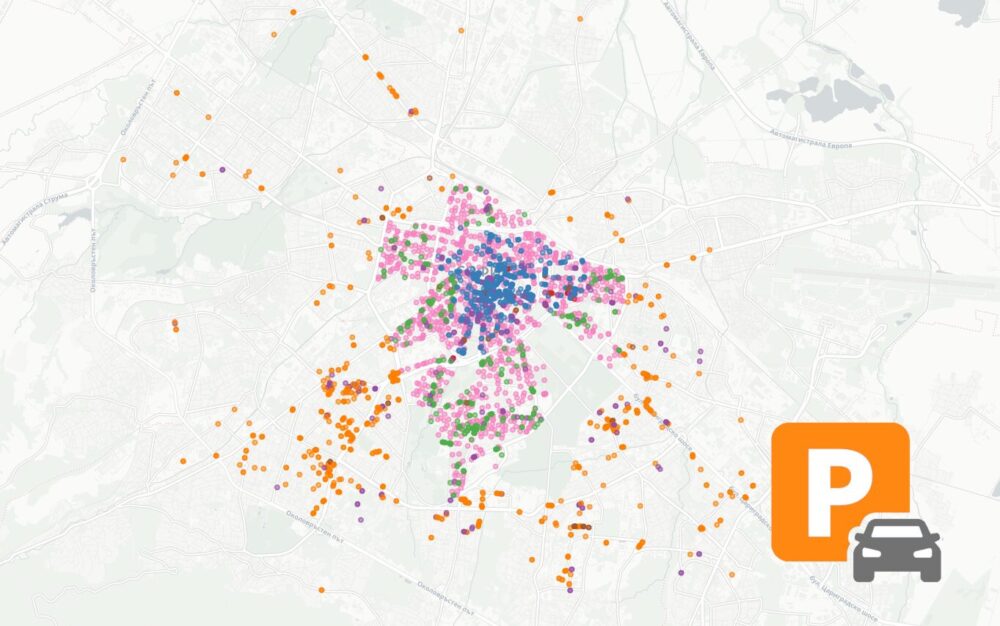
Не, не говоря за пазенето на паркомясто със стол, щайга или саксия.
Преди месец писах за служебното паркиране в София и отправих критика към качеството на данните, които получих тогава. Междувременно пуснах ново запитване по ЗДОИ, с което освен същите данни поисках и всички паркоместа за хора с увреждания. Това беше честа обратна връзка след последната ми карта.
Този път данните бяха в добра форма и практически не се налагаха корекции. Всички данни за абонаменти бяха с имената на платилите ги. Частните лица са с инициали и при тях липсва личен адрес. При фирмите има адрес на централен офис. Данните са абонамента са също много по-добре структурирани – събрани са договорите на едно показвайки какви пакети са групирани. Където има различни периоди на абонамент, това е защото са добавяни пакети на по-късен етап.
Новите данни включват 2246 паркоместа като част от 1317 договора за абонамент с 1048 лица. За сравнение, старата справка от март имаше 48 паркоместа по-малко. Открих само 12 абонамента да са на физически лица. Най-много паркоместа имат ОББ – 51, ДСК – 35, Ц.Б.С. ООД (свързано с хазарт) и Юробанк – по 26, ПИБ 22. Британското посолство има 21 служебни паркоместа. Министерствата имат общо 63, различни агенции – 28, комисии – 15. КТБ още има 3 паркоместа и договорът им е подновен през март тази година. В тези данни не са включени паркоместата, които съдилищата са си осигурили със спорни решения за охранителните зони около сградите си.
Обнових картата да показва новите данни и архивирах картата на друг адрес. Тъй като не се налага да обработвам данните и да гадая, няма паркоместа с неизвестен абонамент. Вместо това добавих категория в легендата за паркоместата запазени за хора с увреждания – общо 1177. За тях се показва като информация само района и зоната. Не получих информация за такива паркоместа извън синя и зелена зона, което е странно. Известни са ми поне няколко паркоместа за хора с увеждания извън тези зони. Попитах ги отново защо липсват.
Обновената карта ще намерите тук или може да я отворите на цял екран.
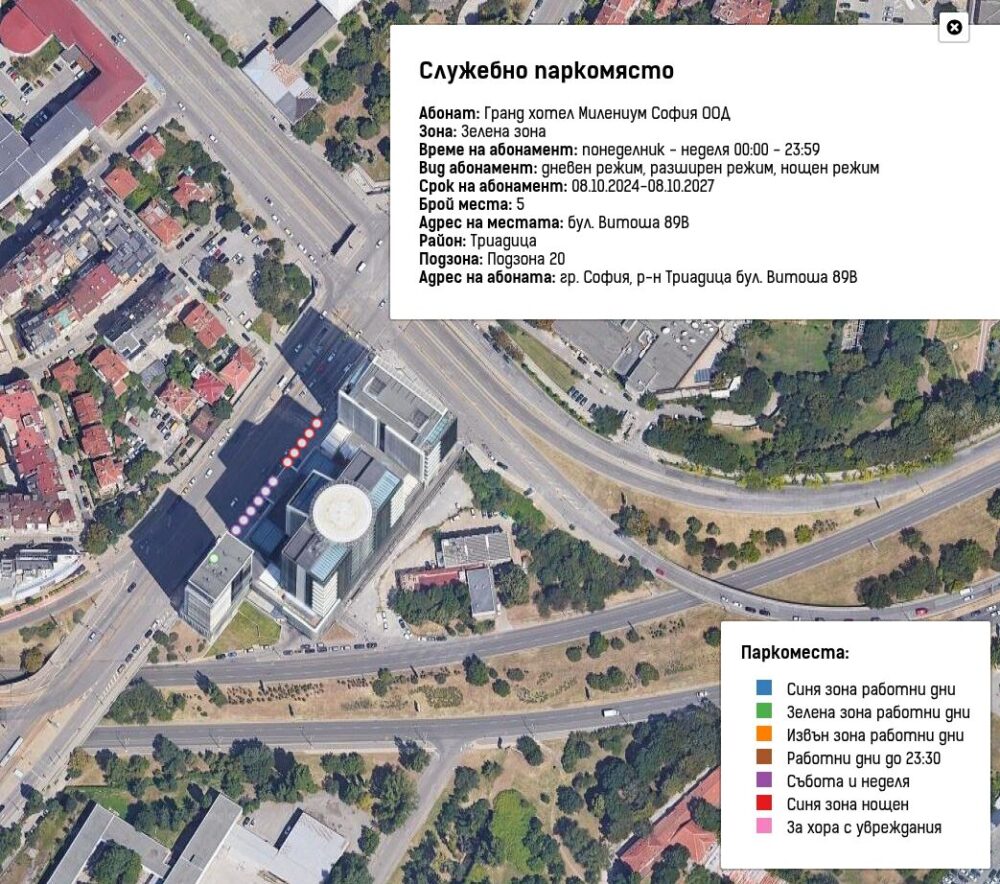
В миналата карта забелязах няколко служебни паркоместа, които имаха нощен режим без да имат основния. Това най-вероятно беше проблем със справката. Този път няма такива, но се забелязва нещо друго странно. Гранд хотел Милениум София ООД са заплатили през ноември 2024-та пет паркоместа с дневен, разширен и нощен режим. Това значи, че местата са резервирани за тях постоянно – понеделник до неделя, 24 часа на ден. Нощният режим обаче е наличен само за синя зона според условията на сайта на ЦГМ. Тези паркоместа се намират в зелена зона и дори справката по моето искане за достъп до данни го показва.
Не става ясно как се е случило това и две години хотелът се радва на денонощни служебни паркоместа почти две години. Възможно е да е било по стара версия на наредбата, но не открих да е имало разлики. Ще питам и ще допълня статията.
В отговора си ЦГМ споделиха и някои финансови данни. Споделят, че за цялата 2025 г. приходите от слъжебен абонамент възлизат на 9.537 млн. лв. или 4.876 млн. € без ДДС. Разходите за осигуряване и поддръжка на служебните паркоместа са 549 хил. лв. или 280.7 хил. € без ДДС. Последното включва само очертаването и слагането на табели, а не махането на погрешно паркирали коли.
Проста сметка показва, че според сега сключените договори приходите без ДДС ще са 505.8 хил. €. Макар броят им и включените пакети да варират, виждам, че се увеличават като брой места в последните години. Така по груби сметки и ако приемем, че всички са се възползвали от намалението от 10% при предплащане за цяла година, биха излезли 5.462 млн. € без ДДС прогнозни приходи за 2026 или 12% повече от предходната. Така предоставените суми за миналата година изглеждат логични като имаме предвид скокът в броя на служебните паркоместа.
Call for topics for the 2026 Maintainers Summit
Post Syndicated from corbet original https://lwn.net/Articles/1082838/
The Maintainers Summit is an annual, invitation-only gathering of kernel
developers and maintainers to discuss development-process issues; see LWN’s 2025 Maintainers Summit coverage for an
example. The call for
topics for the 2026 gathering (Prague, October 8) has gone out.
One of the best ways to obtain an invitation to the Summit is with a good
topic proposal. For best consideration, topics should be submitted before
July 24.
Automated Incident Remediation with AWS DevOps Agent and Kiro CLI
Post Syndicated from Jishnu Dasgupta original https://aws.amazon.com/blogs/devops/automated-incident-remediation-with-aws-devops-agent-and-kiro-cli/
Introduction
Automated incident remediation – turning investigation findings into deployed fixes without manual toil – is the next frontier for operations teams running distributed workloads on AWS. Today, when an incident fires at 2 AM, the on-call engineer must correlate telemetry across Amazon CloudWatch, deployment pipelines, and application logs, then manually write and deploy a fix – a process that routinely takes hours. AWS DevOps Agent addresses the first half by autonomously investigating incidents, identifying root causes, and generating mitigation plans in minutes. During preview, customers and partners reported up to 75% lower MTTR, 80% faster investigations, and 94% root cause accuracy.
But investigation and mitigation recommendations are only half the story. Someone still has to read the findings, write the fix, test it, and deploy it. What if that second half could be automated too?
In a previous post, Leverage Agentic AI for Autonomous Incident Response with AWS DevOps Agent, we demonstrated how to configure AWS DevOps Agent to monitor your applications, trigger autonomous investigations, and follow best practices for production deployments. We also published this code sample which demonstrates how investigations could be wired to be triggered automatically when a Amazon CloudWatch alarm is raised. These two articles now allow you to trigger AWS DevOps Agent investigation on a Amazon CloudWatch alarm and produce a mitigation plan.
In this post, we demonstrate how to integrate AWS DevOps Agent mitigation plan output with Kiro CLI – running in headless mode on AWS CodeBuild – to close the remediation loop end-to-end. When AWS DevOps Agent completes a mitigation analysis, an event-driven pipeline automatically routes the findings to Kiro CLI, which applies the fix to your codebase, creates a pull request for human review, and triggers deployment upon approval. The result: L1/L2 incidents go from detection to deployed fix with minimal manual intervention – the only human touchpoint is the pull request approval.
We walk through the complete solution using a sample CloudFormation application, including the infrastructure code, anomaly generation scripts, event routing, and the Kiro CLI steering configuration that makes it all work. All source code is available in the accompanying aws-samples repository.
Solution Overview
Consider a typical web application running on AWS — a frontend behind an Application Load Balancer, backend compute on Amazon EC2, and an Amazon RDS database, with source code and CloudFormation templates in AWS CodeCommit. When something goes wrong in this environment, the solution chains two AWS frontier agents —AWS DevOps Agent for autonomous investigation and mitigation, and Kiro CLI for automated code remediation — through a fully serverless event-driven bridge to take the application from incident to deployed fix.
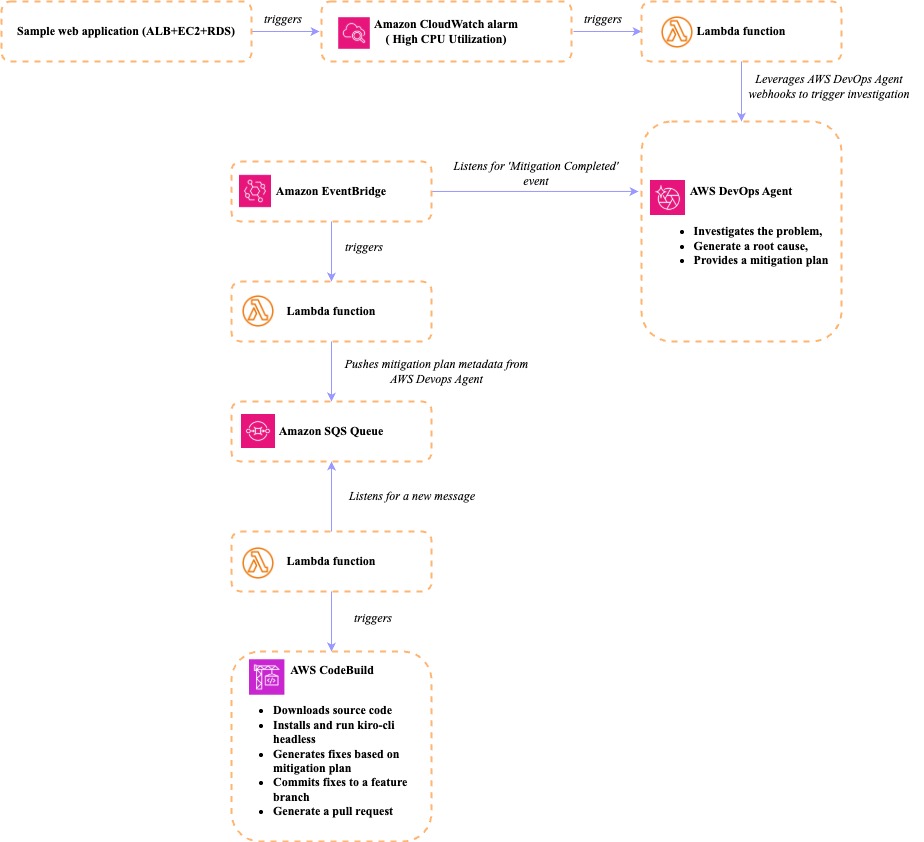
Fig 1 – Solution architecture
How it works
- An incident occurs – Your application experiences an issue – high CPU utilization, elevated error rates, slow response times. Amazon CloudWatch alarms fire.
- DevOps Agent investigates – AWS DevOps Agent, which has your application onboarded into an Agent Space, autonomously correlates metrics, logs, and deployment history to identify root cause and generate a mitigation plan.
- EventBridge routes the signal – An Amazon EventBridge rule captures Mitigation Completed events (source: aws.aidevops) and invokes a AWS Lambda function.
- Lambda extracts and queues – The AWS Lambda function calls the AWS DevOps Agent API to retrieve the mitigation summary and execution plan, then publishes the payload to Amazon SQS queue.
- CodeBuild runs Kiro CLI – When a message arrives in the Amazon SQS queue, a AWS Lambda function with an SQS event source mapping triggers a AWS CodeBuild execution, passing the message content as an environment variable. AWS CodeBuild runs Kiro CLI in headless mode (–no-interactive –trust-tools=read,write,grep,shell), using the mitigation payload as a remediation prompt.
- Kiro CLI applies the fix – Guided by a steering file that describes the repository structure and remediation conventions, Kiro CLI modifies the CloudFormation template or application code, commits to a feature branch, and creates a pull request.
- Human approves, pipeline deploys – A developer reviews the pull request. Upon approval and merge, the associated deployment pipeline gets triggered to execute the change.
Prerequisites
To follow along with this walkthrough, you need:
- An AWS account for AWS DevOps Agent access
- An Agent Space configured
- Kiro CLI with a Pro, Pro+, or Power subscription (required for headless mode API keys)
- AWS CLI configured with appropriate credentials
- The sample repository pushed to your account’s AWS CodeCommit repository
Once completed, follow along the Readme file to setup the components which allow you to implement and execute the above architecture. The sections below provide an explanation of the components that have been built to support the architecture.
Capturing mitigation events
AWS DevOps Agent publishes lifecycle events to the Amazon EventBridge default event bus whenever an investigation or mitigation changes state. Each event uses the source aws.aidevops and a detail-type that identifies the specific like Mitigation Completed, Investigation Completed, or Mitigation Failed. The post focuses on a single signal: the moment a mitigation finishes successfully.
EventBridge rule and Lambda extraction
An Amazon EventBridge rule matching the Mitigation Completed detail-type invokes a AWS Lambda function. The event payload contains metadata (agent_space_id, task_id, and execution_id) which allows the AWS Lambda function to call the AWS DevOps Agent and extracts two key objects: the mitigation summary (what action to take and why) and the execution plan (step-by-step instructions). It publishes this structured payload to an Amazon SQS queue for downstream processing.
Headless remediation with Kiro CLI
With mitigation payloads landing in the Amazon SQS queue, we need a compute environment that can check out the application and infrastructure repository, run Kiro CLI agent against the codebase, and push changes back. AWS CodeBuild is a natural fit — it provides on-demand compute, integrates natively with AWS CodeCommit and requires no persistent infrastructure.
Kiro CLI 2.0 introduced headless mode, which allows it to run programmatically in deployment pipelines without an interactive terminal. You authenticate with an API key (stored in AWS Secrets Manager), pass a prompt, and Kiro CLI executes end-to-end — same tools, same agents, same capabilities as the interactive experience.
How CodeBuild orchestrates the fix
When a message arrives in the Amazon SQS queue, a trigger AWS Lambda function starts a AWS CodeBuild execution, passing the Amazon SQS message body as an environment variable. The AWS CodeBuild buildspec follows a straightforward sequence:
- Install : Installs Kiro CLI and configures the environment. The KIRO_API_KEY is pulled automatically from AWS Secrets Manager ,never hardcoded.
- Generate prompt : A Python script converts the structured mitigation payload into a natural-language remediation prompt. It inspects the content to classify whether the change targets infrastructure (or application code, then generates a focused prompt with the action, reasoning, and specific instructions.
- Create feature branch : Checks out a new branch named after the agent space and execution IDs for traceability.
- Run Kiro CLI : Invokes Kiro CLI chat –no-interactive –trust-tools=read,write,grep,shell with the generated prompt. The –trust-tools flag auto-approves specific tool categories following least-privilege, since there is no human to confirm.
- Validate and commit : Guardrails check the changes: file count limits, protected file detection, Python syntax validation (py_compile), and YAML linting. If all checks pass, the changes are committed and pushed.
- Create pull request : Creates an AWS CodeCommit pull request with the mitigation action as the title and the AWS DevOps Agent reasoning in the description.
The steering file
What makes Kiro CLI effective at remediation – rather than just generating generic code – is the steering file. Steering gives Kiro persistent knowledge about your project: repository structure, coding conventions, and decision frameworks.
For this solution, the steering file serves as the guardrails for automated remediation. It defines:
- Repository structure – Maps each directory to its purpose.
- Decision framework – Rules for classifying changes as infrastructure vs. application.
- Scope constraints – Maximum 3 files per remediation, no new files, no new dependencies, no deletions.
- Protected files – The buildspec, infrastructure pipeline templates, bridge code, and steering files themselves are explicitly off-limits.
- Fail-safe – If the prompt is ambiguous or Kiro cannot determine what to change, it makes no changes rather than guessing.
This steering file is committed to the repository, so every AWS CodeBuild execution picks it up automatically. It ensures Kiro CLI makes targeted, predictable changes rather than broad refactors.
From pull request to deployment
At this point, the automated pipeline has done its work – Kiro CLI has analyzed the mitigation plan, modified the appropriate files, and created a pull request on a feature branch. The pull request description includes what was changed, why (directly from the AWS DevOps Agent’s reasoning), and the agent space and execution IDs for full traceability back to the original incident.
This is where the human-in-the-loop gate comes in. A developer reviews the pull request -verifying that the change is correct, scoped appropriately, and safe to deploy. This approval step is deliberate: while we trust the agents to investigate, analyze, and propose fixes, a human makes the final deployment decision.
Once the pull request is approved and merged into the main branch, the deployment pipelines implement the approved changes in the target environment.
The entire cycle – from CloudWatch alarm to deployed fix – completes in minutes rather than hours, with the only manual step being the pull request review. For organizations handling high volumes of L1/L2 incidents, this translates directly into reduced operational toil and faster recovery.
Cleanup
To avoid ongoing charges, remove the resources created during this walkthrough. Refer to the Readme for the complete teardown sequence.
Conclusion
In this post, we demonstrated how to integrate AWS DevOps Agent mitigation outputs with [1] Kiro CLI to build a closed-loop incident remediation pipeline. By connecting these two frontiers agents’ operations teams can go from incident detection to deployed fix with a single human touchpoint: the pull request approval.
This approach delivers measurable impact for enterprise operations:
- Reduced MTTR – L1/L2 incidents that previously required hours of manual investigation and remediation can now resolve in minutes.
- Improved operator productivity – Engineers shift from reactive firefighting to reviewing and approving targeted, AI-generated fixes.
- Consistent remediation – Steering files codify your team’s conventions and decision frameworks, ensuring every automated fix follows the same standards regardless of when or how often incidents occur.
Ready to get started? Clone the aws-samples repository for the complete implementation, visit the AWS DevOps Agent documentation to configure your first Agent Space, and explore the Kiro CLI documentation to learn more about steering-file-driven code generation. Have questions or want to share how you’ve adapted this pattern? Leave a comment below or open an issue in the repository
[$] Sending packets directly from BPF
Post Syndicated from daroc original https://lwn.net/Articles/1081696/
Tetragon, the BPF-based security monitoring tool,
uses BPF to monitor different aspects of a running kernel and
enforce user-specified policies. It sends its data to a user-space process,
which forwards the data to a central monitoring service elsewhere in the
network, however. This
presents a point of vulnerability: if an attacker can kill Tetragon’s user-space
agent, it won’t be able to properly report on the situation. Song Liu, Mahé
Tardy, and Liam Wiseheart spoke about their work removing the need for the
user-space agent at the 2026
Linux Storage, Filesystem, Memory-Management, and
BPF Summit.
Security updates for Tuesday
Post Syndicated from daroc original https://lwn.net/Articles/1082832/
Security updates have been issued by AlmaLinux (389-ds:1.4, buildah, freeipmi, freerdp, gegl, gimp, golang, kernel, libreoffice, maven:3.9, openexr, perl-DBI, plexus-utils, podman, tomcat, tomcat9, xorg-x11-server, and xorg-x11-server-Xwayland), Debian (imagemagick, p7zip, and redis), Fedora (breezy, calibre, and golang-github-openprinting-ipp-usb), Mageia (ffmpeg, gzip, haproxy, libheif, libtiff, libxml2, packages, perl-List-SomeUtils-XS, and perl-Socket), SUSE (alsa, chromedriver, curl, dhcpcd, docker-compose, glibc, haproxy, ImageMagick, jq, kernel, kubernetes, libpng15, libredwg-devel, libslirp, nghttp2, php8, python-Pillow, python313-Django, python313-weasyprint, qemu, rust-keylime, sccache, and systemd), and Ubuntu (cifs-utils, libexif, libreoffice, libssh2, openssh, and pipewire).
A broken DNSSEC rollover took down .AL. Now 1.1.1.1 tells you when validation is bypassed
Post Syndicated from Sebastiaan Neuteboom original https://blog.cloudflare.com/dnssec-nta-ede-33/
On July 3, 2026, the Albanian communications authority (AKEP), the operator of the .AL country-code top-level domain (TLD) of Albania, attempted a DNSSEC key rollover. Something went wrong, resulting in DNSSEC validation failures. Any validating DNS resolver receiving these signatures was required by the DNSSEC specification to reject them and return errors to clients. That includes 1.1.1.1, the public DNS resolver operated by Cloudflare.
The .AL TLD is the online home of Albanian government services, banks, and media; it ranks #191 on Cloudflare Radar’s TLD ranking. Anyone trying to visit those sites, using a validating resolver, found them unreachable during the incident. The failure had the potential to affect every .AL domain, regardless of where it was hosted or which authoritative nameservers served it.
Just two months earlier, a similar incident struck .DE, the TLD of Germany. As we described in our blog post on the incident, our response was to install a Negative Trust Anchor (NTA) for .DE, temporarily suspending DNSSEC validation in 1.1.1.1 to keep domains reachable while the registry resolved the issue. We did the same for .AL.
NTAs restore resolution, but silently. A client receiving a response served under an NTA has no way to tell, from the response alone, that DNSSEC validation was bypassed, leaving it unable to distinguish a legitimate answer from a spoofed one. For the .AL incident, 1.1.1.1 addressed that gap for the first time, returning a new Extended DNS Error (EDE) code alongside every affected response to signal that the answer was not DNSSEC-validated due to the presence of an NTA.
The graph below shows the SERVFAIL and NOERROR rates for .AL queries on 1.1.1.1 throughout July 3. The SERVFAIL rate climbs as cached records expire and resolvers are forced to revalidate. It drops sharply when the NTA is applied at 17:15 UTC, restoring resolution.

We discussed how DNSSEC works in more detail in our prior blog post. A brief recap:
DNSSEC builds a chain of trust from the root zone down to individual domain names. The root zone holds a Delegation Signer (DS) record for each signed TLD, a fingerprint of that TLD’s DNSKEY. A resolver verifying .AL checks that the DNSKEY served by .AL‘s nameservers matches the DS record in the root. If it does, the resolver trusts that DNS responses from .AL‘s nameservers are authentic. The same pattern repeats one level down: .AL holds DS records for its signed child zones, each with a matching DNSKEY. A break anywhere in that chain, such as a DS record pointing to a key that no longer exists, causes validation to fail for everything below it.
Before the incident, the root zone held a DS record matching the DNSKEY served by the .AL nameservers, as illustrated below.

At around 14:15 UTC, the .AL operator published a new DNSKEY and stopped serving the old one. The DS record in the root zone still pointed to the old DNSKEY (id=26319), so any resolver attempting to validate .AL responses found no matching key and failed.

At roughly 17:00 UTC, the .AL operator removed the new DNSKEY without restoring the old one. The zone now had no DNSKEY records at all, while the DS record in the root still pointed to id=26319, and resolution continued to fail.

At roughly 19:15 UTC, the .AL operator removed the DS record from the root zone. Without a DS record, resolvers no longer expected DNSSEC validation for .AL, and resolution was restored, though the entire TLD was now unsigned.

As of publishing, .AL remains unsigned. The DS record has not been restored to the root zone by the .AL operators. Without a DS record, every .AL domain is unable to use DNSSEC protections.
Having a broken DNSSEC configuration can be painful, especially when it impacts an entire TLD at once. As we covered in our .DE incident blog, recursive DNS operators can install a Negative Trust Anchor (NTA) as defined in RFC 7646, which tells a resolver to treat a zone as unsigned and bypass validation.
Before installing the NTA, we attempted to reach the .AL operator directly and posted on the DNS-OARC Mattermost to alert the community. We received no response, in part because the operator’s contact addresses were themselves under .AL, making them unreachable during the outage.
We applied the NTA for .AL and rolled it out to all 1.1.1.1 users by 17:15 UTC, roughly three hours after the chain broke.
The tradeoff is the same as it was for .DE: a Negative Trust Anchor suspends DNSSEC validation, which means .AL domains were no longer protected against DNS spoofing for the duration. We judged this acceptable for the same reason: the failure was public, confirmed, and affecting every validating resolver equally.
The Negative Trust Anchor was removed the following day, once the .AL operator had removed the DS record from the root zone. With no DS record present, resolvers no longer expected DNSSEC for .AL and the NTA was no longer needed.
Installing a Negative Trust Anchor is an aggressive measure. We suspend DNSSEC validation to keep domains reachable, accepting that responses are no longer cryptographically verified for the duration. Users get answers instead of SERVFAIL, but those answers carry no DNSSEC guarantee.
What makes this harder is that, up until now, nothing in the DNS response signalled this to the client; a response served under an NTA looked identical to a fully validated one. RFC 7646 acknowledges this gap and recommends that operators publicly disclose which NTAs they have in place, but that disclosure is out-of-band. For both the .DE and .AL incidents we published status pages, but a status page requires the user to go looking. An application, a monitoring tool, or a user querying 1.1.1.1 had no way to tell, from the response alone, that DNSSEC validation was bypassed.
Extended DNS Error (EDE) codes, defined in RFC 8914, allow resolvers to include additional context alongside any DNS response, whether that is an error or a successful answer. Babak Farrokhi at Quad9 proposed an Internet-Draft to signal the presence of a Negative Trust Anchor directly in the DNS response, using a new EDE code: Disclosure of Negative Trust Anchors in DNS Responses. We joined as co-authors, and 1.1.1.1 now implements it.
During the .AL incident, any query for a .AL name returned both the answer and the new EDE code while the Negative Trust Anchor was installed. Here is what that looked like:
$ kdig @1.1.1.1 google.al
;; ->>HEADER<<- opcode: QUERY; status: NOERROR; id: 32848
;; Flags: qr rd ra; QUERY: 1; ANSWER: 1; AUTHORITY: 0; ADDITIONAL: 1

;; EDNS PSEUDOSECTION:
;; Version: 0; flags: ; UDP size: 1232 B; ext-rcode: NOERROR
;; EDE: 9 (DNSKEY Missing): 'no SEP matching the DS found for al.'
;; EDE: 33 (Negative Trust Anchor): 'a Negative Trust Anchor has been applied for this query (see RFC 7646)'

;; ANSWER SECTION:
google.al.              300    IN    A    142.251.142.196
The response is a NOERROR with a valid answer: google.al resolves, but two EDE codes accompany it. EDE 9 (DNSKEY Missing) surfaces the underlying DNSSEC failure: the chain of trust was broken and validation failed. EDE 33 (Negative Trust Anchor) signals that 1.1.1.1 applied a Negative Trust Anchor and served the response anyway. Together they give clients and operators full visibility into what happened: the answer is real, but it was not DNSSEC-validated.
1.1.1.1 returns EDE 33 on any response generated while an NTA is active, regardless of whether the query itself would have failed DNSSEC validation. A query for a domain that does not use DNSSEC at all will still carry EDE 33 if it falls under an active NTA. This is intentional: the NTA covers the entire zone, and transparency applies equally to every response served under it.
This also resolves an issue we flagged in our .DE blog, where 1.1.1.1 incorrectly returned EDE 22 (No Reachable Authority) instead of surfacing the underlying DNSSEC error. During the .AL incident, 1.1.1.1 correctly returned EDE 9 (DNSKEY Missing) alongside EDE 33.
The Internet-Draft is an individual submission and EDE 33 has been assigned by the Internet Assigned Numbers Authority (IANA). Thanks to our co-author, Babak Farrokhi at Quad9, the kdig tool from the Knot project now recognizes EDE 33 by name, and a pull request for Unbound is under review. We hope other resolver implementations will follow. The Internet-Draft has been submitted to the Internet Engineering Task Force (IETF) DNSOP Working Group, and will be discussed at the IETF meeting taking place in Vienna from July 18 to July 24.
TLD-level DNSSEC failures are rare, but when they happen they affect every domain underneath the affected TLD simultaneously, and every validating resolver equally. The .AL incident, following closely behind .DE, shows that Negative Trust Anchors are a necessary operational tool, but one that has, until now, been invisible to the users they affect.
EDE 33 closes a gap that RFC 7646 left open. A response served under a Negative Trust Anchor now says so directly, giving operators, monitoring tools, and users the information they need to understand what the resolver did and why.
The Internet-Draft is available at the IETF datatracker. If you have thoughts on it, the IETF DNSOP mailing list is the right place to share them.
If you want to learn more about how DNSSEC works, visit our page How does DNSSEC work? And you can always follow real-time DNS trends and TLD data on Cloudflare Radar.
CVE-2026-55040: Microsoft SharePoint JWT Token Authentication Bypass (FIXED)
Post Syndicated from Stephen Fewer original https://www.rapid7.com/blog/post/ve-cve-2026-55040-microsoft-sharepoint-jwt-token-authentication-bypass-fixed
Overview
Rapid7 Labs conducted a zero-day research project against Microsoft SharePoint, resulting in the discovery of two new vulnerabilities that, when chained together, achieve unauthenticated remote code execution (RCE) against a vulnerable SharePoint server. Today, both Rapid7 and Microsoft are disclosing the first vulnerability in this chain, the authentication bypass vulnerability CVE-2026-55040. The RCE component of the exploit chain is expected to be patched by Microsoft in the next update cycle for August 2026. The exploit chain was developed as an entry for the recent Pwn2Own Berlin hacking competition – part of Rapid7 Labs’ continued effort to raise the bar in Vulnerability Intelligence and our commitment to the preemptive protection of our customers through original vulnerability research.
A remote unauthenticated attacker can leverage CVE-2026-55040 to bypass authentication on a vulnerable SharePoint server and perform operations as a SharePoint site user or administrator. The vulnerability is due to several issues in the JWT token validation pipeline.
CVE-2026-55040 has a CVSSv3.1 score of 5.3 (Medium), and a Common Weakness Enumeration (CWE) of CWE-1390: Weak Authentication.
Product description
Microsoft SharePoint is a ubiquitous, web-based collaboration and document management platform deeply integrated into the Microsoft 365 ecosystem. Serving as the central hub for corporate intranets, internal file sharing, and workflow automation, it is trusted by enterprises worldwide to store and manage vast repositories of sensitive business data. Because SharePoint acts as a critical bridge between internal users, active directories, and cloud infrastructure, vulnerabilities within its architecture present a high-risk attack surface.
Impact
By leveraging CVE-2026-55040, a remote unauthenticated attacker can assume the identity of any SharePoint site user; the prerequisite is the attacker must know in advance the user they wish to identify as. This can be achieved in a number of ways, including via a user’s Active Directory (AD) Security ID (SID), or via a user’s AD User Principal Name (UPN). A UPN is the primary logon name for a user in either Windows AD or Microsoft Entra ID, and is formatted similar to that of an email address, e.g. [email protected].
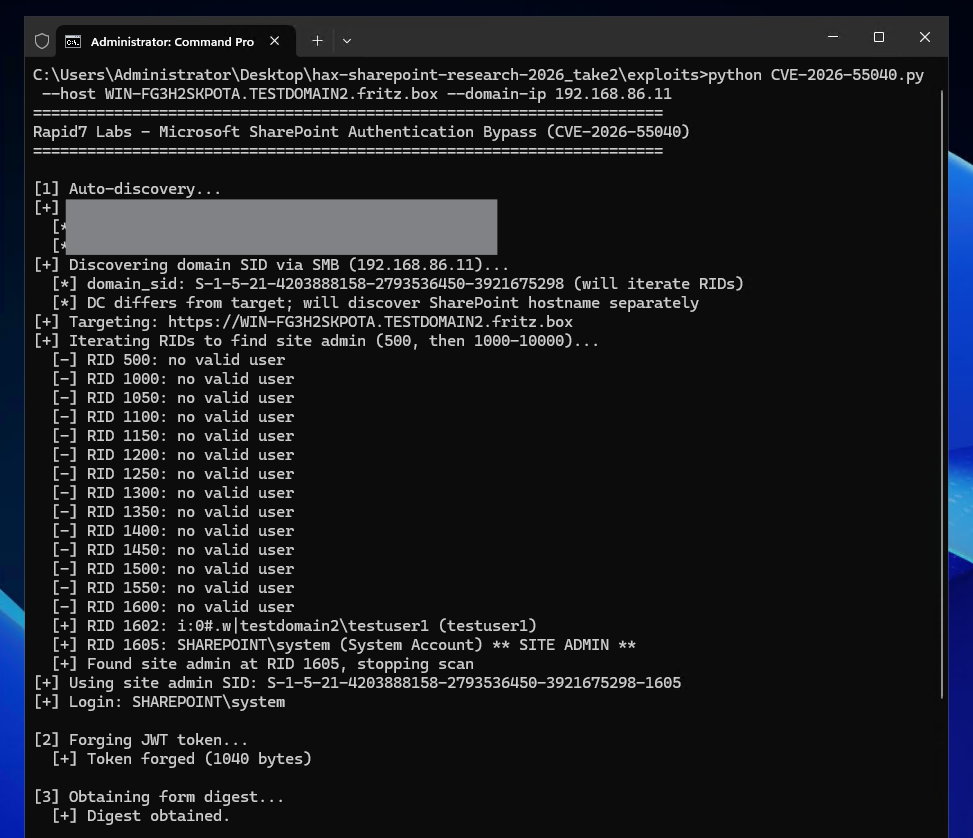
In the example screenshot below, with identifying information redacted, a Rapid7 Labs proof-of-concept script discovers potential SharePoint users via SID enumeration and then leverages CVE-2026-55040 to bypass authentication on the target SharePoint site to assume the identity of that user — ultimately identifying the SharePoint site administrator user account.
⠀
An attacker who successfully exploits CVE-2026-55040 can perform operations against the target SharePoint site as the user they identify as. Furthermore, this authentication bypass can be chained to additional vulnerabilities within the authenticated attack surface of the target site.
Rapid7 Labs has chained the authentication bypass CVE-2026-55040 with a separate RCE vulnerability for unauthenticated RCE. Patching CVE-2026-55040 will successfully break this exploit chain. The RCE component has been disclosed to Microsoft and is expected to be patched in the scheduled August patch cycle. The chaining of vulnerabilities highlights that even though the authentication bypass has been assigned a medium severity CVSS score by Microsoft, the impact of successfully chaining a medium severity authentication bypass to an RCE component is significant. This also underscores the importance of patching vulnerabilities such as authentication bypasses, which can break complex and high impact exploit chains.
Leveraging AI
To develop our SharePoint exploit chain, Rapid7 Labs undertook a research project divided into two main sprints, the first in January and the second in March, 2026. While both sprints did encompass more traditional vulnerability research such as manual code review and reverse engineering, a significant amount of the work was undertaken through an agent. Over 24 active days of agentic work, we leveraged 96 sessions, issued 256 prompts, and generated approximately 80,000 agentic tool calls.
The initial January sprint was unsuccessful, resulting in no findings that could be leveraged for an exploit chain. We used this sprint to experiment with several different publicly available models, along with different workflows to navigate and reason across a massive and complex codebase. However, our second sprint in March was successful and yielded, through a heavily prompted agent, a two-vulnerability exploit chain that achieved unauthenticated RCE.
The improvement in quality between January and March in terms of agentic work, along with our improved workflows, was noticeable. This highlights the speed at which this field is evolving, how publicly available models are improving, and how as research teams develop their workflows, the results begin to compound.
Credit
This vulnerability was discovered by Stephen Fewer, Senior Principal Security Researcher at Rapid7 and is being disclosed in accordance with Rapid7’s vulnerability disclosure policy.
Vendor statement
The following statement has been provided by Microsoft:
“We would like to thank Rapid7 for responsibly reporting this issue through coordinated vulnerability disclosure.”
Technical analysis
Rapid7 will be publishing full technical details for CVE-2026-55040 within 30 days of this disclosure.
Remediation
Customers are advised to apply the latest available updates for the impacted product to ensure they are protected.
Rapid7 customers
Exposure Command, InsightVM and Nexpose customers will be able to assess their exposure to CVE-2026-55040 with Authenticated vulnerability checks available in the July 14 content release
Disclosure timeline
-
May 18, 2026: Rapid7 discloses an unauthenticated RCE exploit chain to Microsoft. Microsoft acknowledges receipt of the disclosure the same day.
-
May 20, 2026: Microsoft confirms the findings and indicates that the exploit chain will be patched across two scheduled update cycles – the authentication bypass component in July, and the RCE component in August.
-
May 21, 2026: Rapid7 acknowledges the disclosure schedule and requests supporting information. Microsoft requests a 30 day stay on disclosure of technical details and publication of PoC.
-
May 29, 2026: Rapid7 agrees to a 30 day stay on technical details with a proviso to publish earlier should either exploitation in-the-wild or third-party publication of details occur within the 30 days. Microsoft confirms the disclosure plan the same day.
-
June 30, 2026: Rapid7 requests supporting information for the upcoming disclosure.
-
June 30, 2026: Microsoft provides supporting information to Rapid7.
-
July 14, 2026: This disclosure for CVE-2026-55040.
THG Video Podcast: Counterfactuals – 1527 Sack of Rome
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=H53cmfsa_Fo
Vulnerability in FIFA’s Network
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/vulnerability-in-fifas-network.html
FIFA’s network was vulnerable to anyone with even minimal access.
AI literacy begins with data literacy: An example from healthcare
Post Syndicated from Bobby Whyte original https://www.raspberrypi.org/blog/ai-literacy-begins-with-data-literacy-an-example-from-healthcare/
The development of AI and data science has transformed how we gain insights from data. In healthcare, AI tools are being used in the development of new treatments as researchers apply machine learning methods to datasets. However, applying AI in healthcare also brings risks, particularly when systems amplify existing biases in data or design.
In our fourth seminar in our current series on teaching about AI in the arts, humanities, and sciences, Kathy Jessen Eller (The Concord Consortium) introduced the Data Science, AI & You (DSAIY) programme, a high school curriculum that helps students critically evaluate the role of data and AI in healthcare.
The role of critical thinking skills in AI education
Kathy began her seminar by arguing that for many students who use AI tools in their coursework, questions remain about whether they are critically evaluating the tools’ outputs. Students may or may not check an AI-generated answer against primary sources to see if the answer is accurate. There is also growing concern that students’ use of AI tools lets them offload cognitive work rather than engage in deeper thinking. This presents a challenge for educators: how do we help students use AI productively while still supporting them to develop the critical judgement needed to evaluate its outputs?
Introducing Data Science, AI & You (DSAIY)
To tackle this challenge, Kathy and her colleagues have developed the Data Science, AI & You (DSAIY) programme (pronounced ‘Daisy’). DSAIY is a semester-long high school curriculum designed to introduce students to AI by actively engaging them in the machine learning process.
The programme introduces machine learning as the engine behind many AI tools, and introduces the concept of bias through real-world examples. Students use a variety of tools to collect and prepare data, train, test, and evaluate models. It culminates in an ‘AI-a-thon’ where young people work in cross-disciplinary teams alongside data scientists, clinicians, and their own teachers to gain real-world experience.
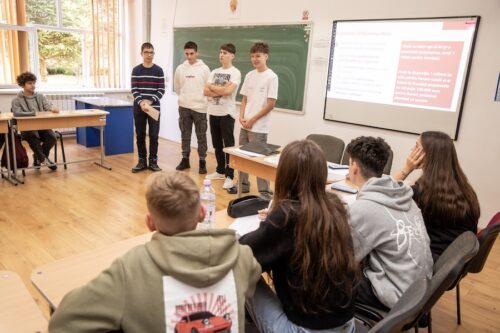
At the time of the seminar, 11 teachers had delivered the programme to over 800 students across a variety of settings in Rhode Island, USA. Teachers are heavily supported with four days of professional development and ongoing technical assistance throughout implementation. The students that took part had a wide variety of prior experience, including many with no prior background in computer science or statistics. Female participation is notably high; one teacher even remarked that the course saw more girls enrolled than any of his other computer science classes.
Hands-on with machine learning
In DSAIY, students experience the full machine learning pipeline from data collection and data preparation, to modeling and deployment. Using Python, they train and test simple machine learning models on authentic healthcare data. The aim of the programme is to move students from basic graphing to evaluating complex models, transitioning them from merely plotting data to deeply reasoning about it.
The programme makes use of CODAP (the Common Online Data Analysis Platform), a free, web-based tool developed by The Concord Consortium. CODAP provides an interactive, highly visual environment that lowers the barrier to entry. Students can visualise large datasets and click into individual data points, allowing them to see individual cases within a larger dataset.
Understanding bias in healthcare systems
The curriculum uses real-world examples from healthcare to introduce concepts of bias and fairness. For example, students learn about pulse oximeters, which estimate blood oxygen levels. However, as these use red and infrared light, readings can vary depending on skin pigmentation, which can lead to inaccurate readings.
Students also collect their own blood oxygen data and plot it using CODAP to observe variability. They consider the accuracy of their measurements and grapple with the ethics of removing outliers from a dataset. This led to students asking critical questions about the makeup of their datasets, the context in which data are collected, and the implications of how data are used in healthcare.
Through the DSAIY programme, Kathy reported that students developed stronger data reasoning skills, gained a deeper awareness of inherent AI biases and risks, and built confidence in public speaking and collaborating with others. Students were also highly engaged and appreciated the focus on real-world healthcare applications and their social implications.
The importance of data literacy for AI literacy
Kathy concluded the seminar by arguing that AI literacy must start with data literacy. When students learn to examine, question, and reason about the data behind AI technologies, they develop the critical thinking skills needed to engage with outputs from real-world systems or everyday technologies like ChatGPT. This can then help them evaluate both the trustworthiness of these tools and their role in important decision-making processes.
You can watch the seminar here:
If you are interested in learning more about Kathy’s work, you can read about the DSAIY programme here or you can read the paper here. You can also learn about CODAP, the data visualisation tool featured in this seminar here.
Join our next seminar
In our current seminar series, we’re exploring how AI is taught across the curriculum. In our next seminar on Tuesday 14 July at 17:00–18:30 BST, we welcome Dan Verständig (Goethe University Frankfurt) who will explore the connection between Social explainable AI (Social XAI) and Critical Computational Literacy (CCL). To take part in the seminar, click the button below to register. We hope to see you there.
The schedule of our upcoming seminars is available online. You can catch up on past seminars on our blog and on the previous seminars and recordings page.
The post AI literacy begins with data literacy: An example from healthcare appeared first on Raspberry Pi Foundation.
Rapid7 and Mindshare Partner to Accelerate Cyber Resilience Across the Middle East
Post Syndicated from Gopan Sivasankaran original https://www.rapid7.com/blog/post/c-rapid7-mindware-middle-east-cybersecurity-partnership
Gopan Sivasankaran is Regional Director, Middle East & Africa, at Rapid7
From AI adoption and cloud-first strategies to smart cities and critical infrastructure modernization, organizations across the United Arab Emirates are embracing innovation at an unprecedented rate. The country truly is setting the pace for digital transformation.
Against this backdrop of rapid innovation, today’s security teams are managing increasingly complex environments while defending against more sophisticated, AI-enabled threats. In this environment, business leaders still expect security to enable innovation, not slow it down. They’re pushed to reduce risk, improve visibility across expanding attack surfaces, and respond faster than ever before, with limited resources now table stakes.
This shift is changing what organizations expect from their cybersecurity partners, with customers no longer wanting disconnected tools or transactional relationships. They’re instead craving trusted advisors who can help simplify security operations, strengthen cyber resilience, and deliver measurable outcomes.
That’s why Rapid7 is excited to announce a new strategic, Middle East-spanning distribution partnership with Mindware.
A shared commitment to the region
The Middle East continues to establish itself as one of the world’s most ambitious digital economies. As organizations invest in cloud technologies, AI, and connected infrastructure, cybersecurity has become a critical foundation for sustainable growth.
This is precisely why Rapid7 has continued to invest in the Middle East: We recognize the region’s growing importance to the global cybersecurity landscape, and this new partnership with Mindware represents another important step in that journey.
This collaboration is about more than expanding our channel presence, it’s about investing in the partners helping organizations navigate an increasingly complex security landscape.
Mindware has built a strong reputation as one of the Middle East’s leading value-added distributors, combining deep regional expertise with technical enablement, professional services, and an extensive partner ecosystem. Together, we’re creating a framework that helps partners grow their cybersecurity practices while delivering greater value to customers.
Building stronger security operations
Security teams today face a common challenge: too many tools, too many alerts, and not enough time. Organizations are increasingly looking for platforms that bring exposure management, threat detection, and response together to improve visibility and reduce operational complexity.
Rapid7’s AI-powered cybersecurity operations platform helps organizations unify security operations, reduce risk, and respond to threats with greater speed and confidence. Combined with Mindware’s regional market knowledge, partner enablement capabilities, and technical expertise, this partnership will make it easier for organizations across the Middle East to access modern cybersecurity operations through trusted local partners.
For those partners, this creates new opportunities to expand managed services, strengthen technical capabilities, and help customers modernize their security operations while supporting long-term business growth.
Local expertise alongside global innovation
The most successful cybersecurity partnerships combine global innovation with local knowledge. Organizations want world-class technology, but they also expect partners who understand their business environment, regulatory landscape, and operational priorities.
By combining Rapid7’s cybersecurity innovation with Mindware’s established regional ecosystem, we’re helping partners fortify and deliver solutions capable of addressing today’s unprecedented security challenges and threats.
Together, we’ll invest in partner enablement and technical training programs designed to help build stronger security practices and create long-term customer success.
Looking ahead
Cyber resilience is no longer just a technology objective; it’s a business imperative. As organizations across the Gulf continue to accelerate digital transformation, security teams need solutions that reduce complexity, improve operational efficiency, and help them stay ahead of an evolving threat landscape.
Rapid7 and Mindware share a common belief that the future of cybersecurity is built through collaboration. By bringing together global cybersecurity innovation, regional expertise, and a shared commitment to partner success, we’re helping organizations across the Middle East strengthen cyber resilience while enabling partners to grow with confidence.
We’re excited about what’s ahead and look forward to working with our partners to build a stronger cybersecurity ecosystem across the region.
Ready to grow with Rapid7? Learn more about the Rapid7 PACT Partner Program and discover how we’re helping partners deliver stronger cybersecurity outcomes across the Middle East.
Красота и катастрофа в „Светлосянка: Експедиция 33“
Post Syndicated from original https://www.toest.bg/krasota-i-katastrofa-v-svetlosyanka-ekspeditsiya-33/
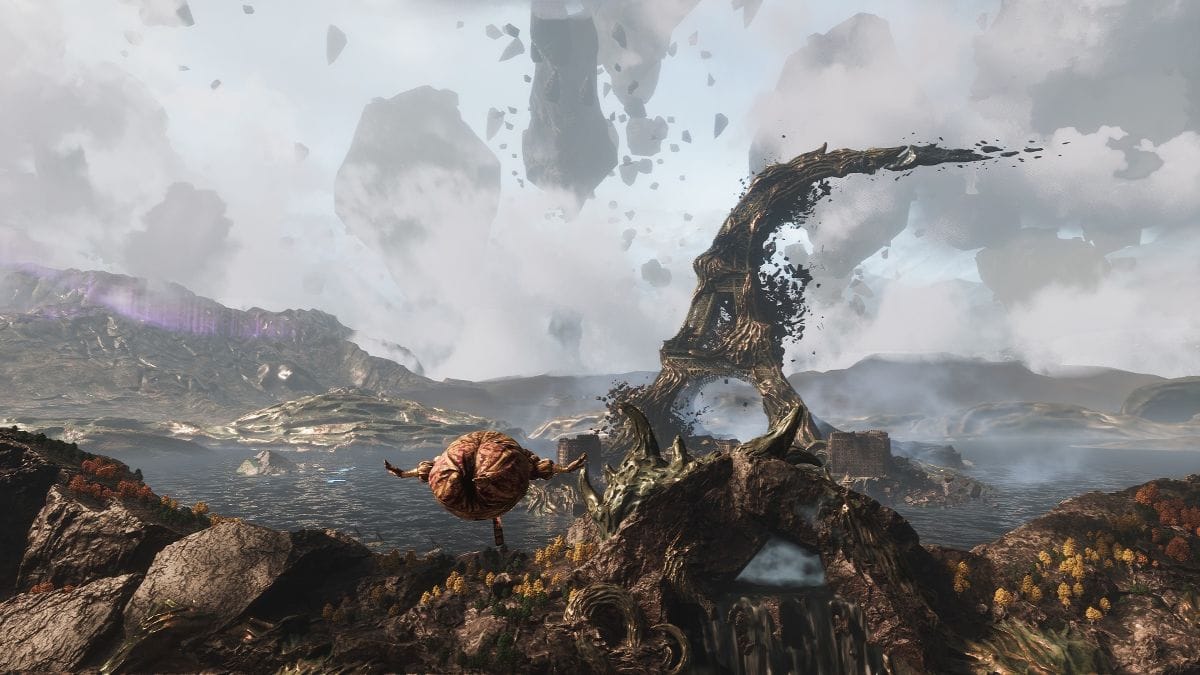
Северина Станкева: Поводът за този разговор е игра, която се появи миналата година като че ли отникъде и постигна невероятен успех и в лицето на публиката, и в това на критиката, толкова по-учудващ за дебютна игра на студио, за което също никой не беше чувал нищо – „Светлосянка: Експедиция 33“ (Clair Obscur: Expedition 33) на Sandfall Interactive. Когато ти я препоръчах, ти имаше поне две резерви към нея. Едната беше спрямо музиката, за която, съдейки от трейлъра, каза, че е „противна“ и „няма да я изтрая“, а другата – по отношение на стила битка, която определи като „наивна“. И за музиката, и за битките ще стане дума, но предлагам да започнем от като че ли реабилитиращото я в твоите очи художествено качество, заради което ми се струва, че в последна сметка я оцени толкова високо. Както се изрази по-късно, „Светлосянка“ е реквием на френската цивилизация, в което има нещо дълбоко антиутопично. Кое е собствено антиутопичното в нея? Това не е игра, която би била поставена в жанра (ако въобще е жанр, но това е друга тема) на антиутопията. Интерпретациите ѝ по-скоро се движат в трагическия ключ на семейната драма.
Миглена Николчина: Играта ни въвежда в един много красив, но разпадащ се свят, който някъде по средата се оказва, че не е истинският. Тази неистинност обаче е може би истината, тоест оказва се алегория на мъртвата вече Франция на живописта, операта, елегантността, цивилизоваността… Какво по-антиутопично от това? Що се отнася до оплакванията ми от музиката, те касаеха един конкретен момент; оплакванията ми от битките също засягат специфичен аспект, иначе веднага оцених хореографията им. Възможно е обаче да съм пренесла в тези си реакции смразяващия първоначален ефект на играта върху мен. Ще кажа и за него. Както предлагаш, ще се върнем към тези теми.
Като начало нека не се занимаваме много с онова, което най-вече занимаваше публиката по форумите – семейната драма. Тази семейна драма хората сериозно я разнищват, а на мен дори ми е забавна. Ако се погледне психоаналитично на нея, човек може и да се посмее. Под разни претексти родителите са готови да изтребят децата си, децата да изтребят родителите си, сестрите се бият на живот и смърт, накрая братът и сестрата също… И всичко това е, защото майката твърде много обича сина си; бащата – майката и дъщерята; сестрата – брат си… Сюжетът на играта систематично отстранява всички любовни или квазилюбовни претенденти, които не са част от тази инцестна въртележка. Във видеоигрите от самото им зараждане в центъра се поставят едипални битки с бащински властови фигури („босове“) и съвсем откровено с абектни репрезентации на майката – говорили сме за това, а и ти си го обсъждала подробно в изследването си за жените чудовища. В „Светлосянка“ обаче поразяват пищната многотия и оголването на фройдистко-еротичния аспект на конфликтите.
Но да се върна към антиутопията, тема, по която също вече сме говорили – ти и аз, аз и Еньо Стоянов… Говорили сме за специфичния тип руини, върху които се разгръщат едни или други дистопийни сюжети. С Еньо сме обсъждали как в „Ядрена зима“ (Fallout), особено в „Ню Вегас“ (New Vegas), руините са на загиналата американска средна класа. Това, което виждаме там, е провалът на проекта – на утопията – за средната класа. В „Метро“ (Metro) виждаме колосалните руини на комунистическия проект – там пък ядреният апокалипсис се разполага върху тези останки. В „Диско Елизиум“ (Disco Elysium) виждаме руините на специфично естонски исторически пластове, виждаме и такива, които се отнасят до краха на просветителския проект като цяло, има и слой, свързан с провала на комунизма, на прехода след него.
И ето че в „Светлосянка“ виждаме Париж. Париж е показан в три локации, които са в различна степен и форма на разруха. В единия играта започва и завършва, като този град присъства в три отделни времеви порядъка – естетизиран, но обхванат от обезпокоителни метаморфози в началото; халюцинаторно видоизменен в последното действие; най-сетне, тревожещо странен в единия от двата възможни финала. Това е част от Париж, „нарисувана“ и отцепена от цялото – музейна изрезка, в която най-важната сграда е операта.
Вторият Париж е напълно разрушен, отломъци от грамадни сгради висят във въздуха над купчина от архитектурни цепнатини и пламтящи пропасти. Има и трети – на разложението, разплут от просмукваща го неназована поквара. Всъщност има и един четвърти в „истинския“ финал на играта: в него Айфеловата кула е буквално фон на гробище.
За мен това визуално издевателство над някогашната световна столица на изкуството беше най-силното преживяване в играта, както и въобще нейната художническа и бих казала, изкуствоведска страна. Музиката отнесе най-много възторзи, тя също допринася за това, което виждам: един реквием. Но живописната страна на тази игра, в която всички персонажи са художници, за мен е най-сериозният носител на смисъла ѝ. Признавам, добра е музиката! Оплакването ми беше от момента, когато безкрайно тегаво се движиш из една равнина на фона на протяжна кахърна песен. Едвам пълзиш, а тя се върти и върти. И няма спасение! Има музика, която търпи повторение, дори да е видиотяващо, и има музика, чието повторение в един момент става непоносимо – може би тъкмо поради изобилната ѝ съдържателност.
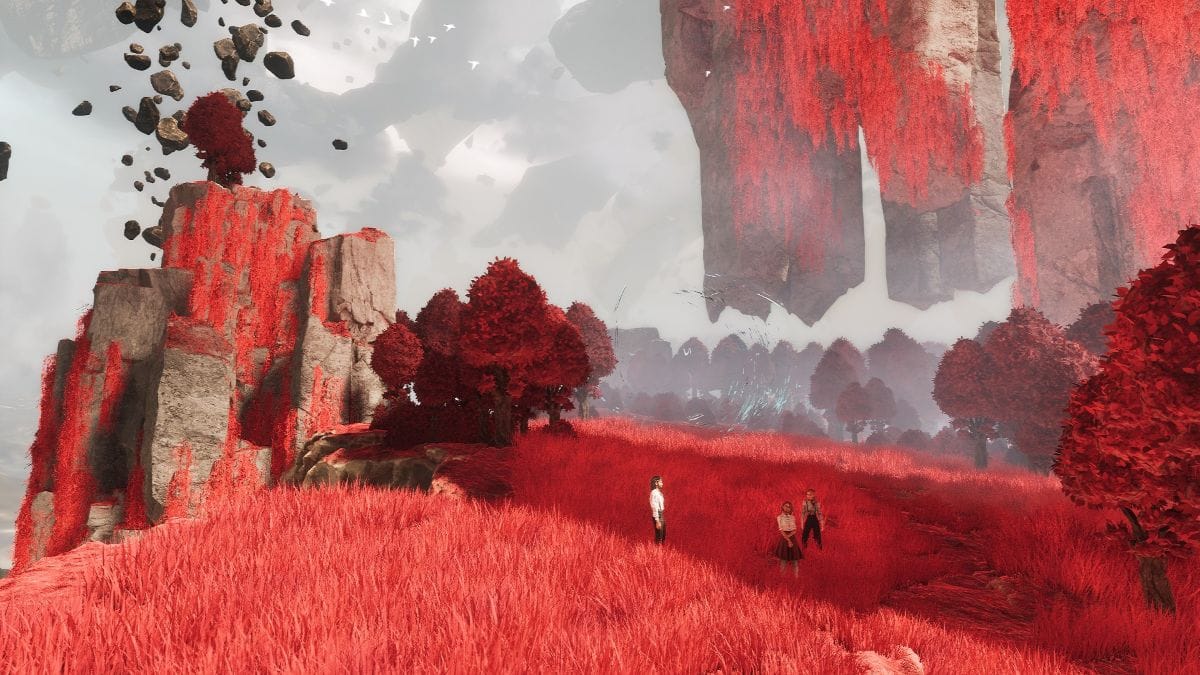
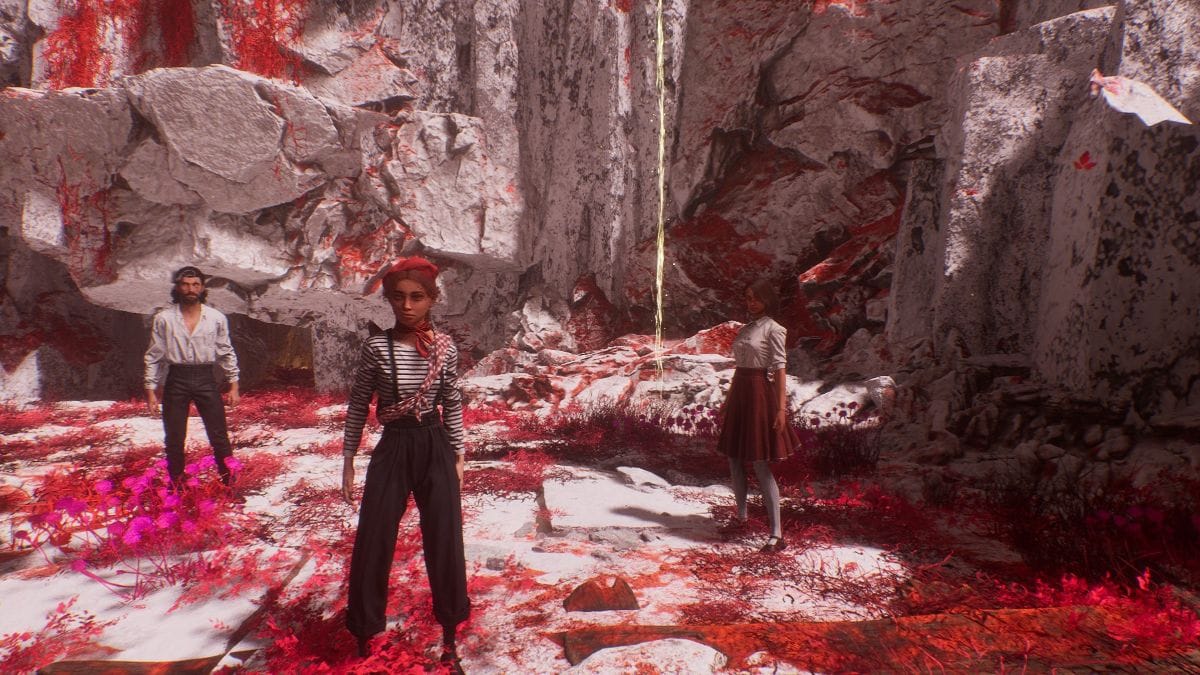
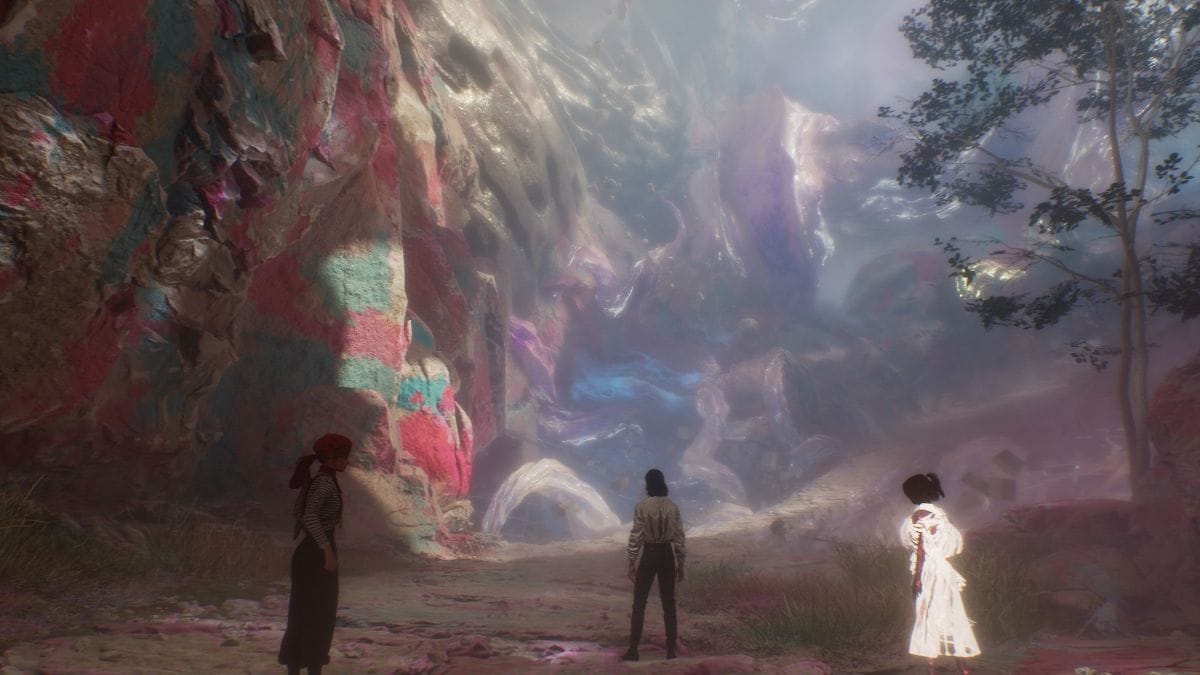
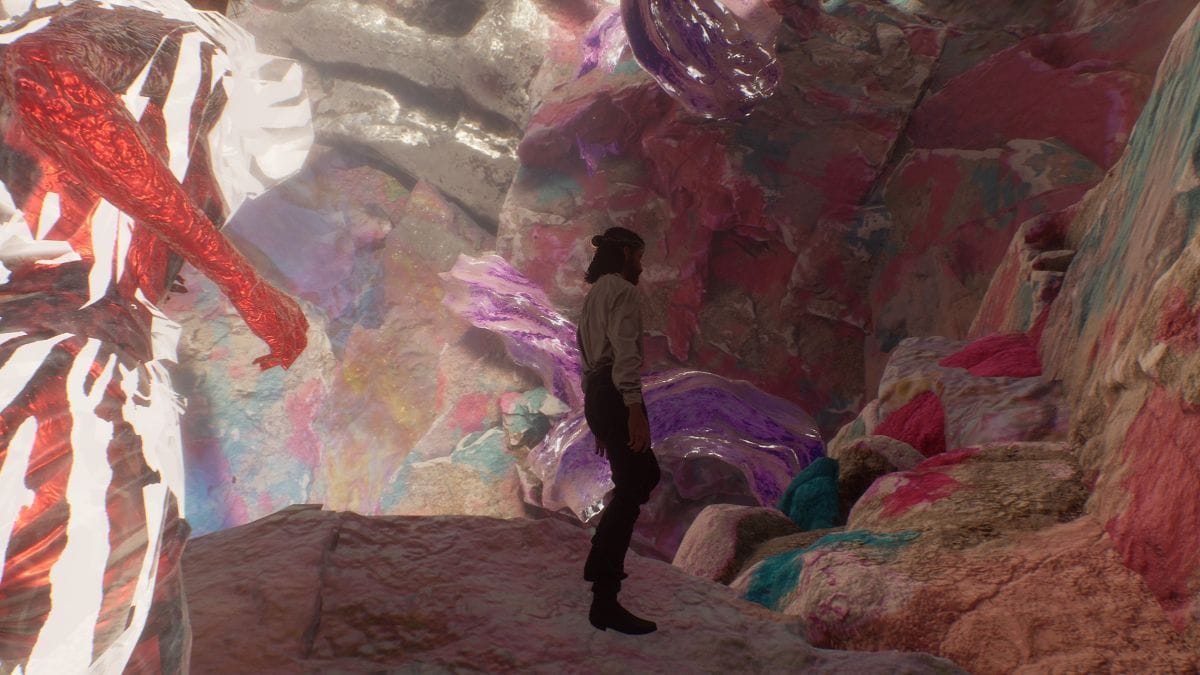
Кадри от „Светлосянка“
Северина Станкева: Ефектът с повторението е търсен според мен. Набиващата се тема от началото ми беше дори симпатична, докато постепенно не се превърна в рококо кошмар без изход, някак още по-жесток заради лекотата си. Това се връзва и сюжетно. Освен това имам съмнението, че при теб ефектът е бил още по-силен, защото си прекарала доста повече време на съответните места, отколкото средностатистическия играч.
Миглена Николчина: Така е, аз съм много подробна, но не съм единствената. Във форумите предлагаха модове за тази локация, но аз започнах просто да изключвам звука. Що се отнася до битките, мисля, че беше грешка да играя на средно ниво, което по принцип винаги правя. То се оказа тежко – но оплакването ми не е от това, че е тежко, а от това, че тази тежест създава лудонаративен дисонанс. При много игри битките са гладко интегрирани или въобще играта е битките, там няма какво друго да очакваш. Но в „Светлосянка“ трудността на тези битки, времеемкостта им може да смажат сюжета, персонажите и най-вече ефекта от това, което може да се нарече онтологическа катастрофа: продънването на реалността в света на картината. Битките сами по себе си са красиви, противниците са живописни, смешно-страшни, за да го кажем с една естетическа категория на Хофман. Получава се разминаване обаче между ангажираността на играча с тях и залозите на другите аспекти на играта.
Северина Станкева: Съгласна съм, че има дисонанс между логиката на действията на играча и тази на разказа, но помоему едно от нещата, които тази игра съумява да направи изключително добре, е да съвместява такъв тип противоположности (точно както изобразителната техника, на която дължи името си), и то така, че моментите на дисонанс са някак инкорпорирани в цялото, без то да страда от това, напротив. С други думи, този разрив може да се разгледа като аспект на онтологическата катастрофа. Като голям фен на стила битка на „Секиро“ (Sekiro), търпението и дисциплината, които тя изисква, „Светлосянка“ много ми допадна в чисто действено отношение. Тя разширява арсенала от възможности на ритмичната битка, добавяйки походови елементи, които също – давам си сметка, че това е субективно предпочитание – ми се видяха освежаващи. Но отвъд личните предпочитания, несъвпадението между битка и разказ всъщност много добре ми се върза с контрастното построение на самия разказ, в който също хем има толкова наивни и детски елементи, хем е изключително мрачен и накъсван от постоянното врязване на трагедии. Темите на играта са смъртта и загубата и това как да им устоим, как да се справим с тях. Битките се случват на ниво, което е онтологически различно (по-художествено, по-наивно) от пласта на реалността (или това, което се приема за реалност в самия разказ). За това ще стане въпрос по-късно. Мисълта ми е, че при тях има двойна дистанция, която в началото не се разкрива като такава – игра в играта. Тоест аз хем съм съгласна, хем за мен лично дисонантното е много силно качество, не недостатък. Малко са игрите, които успяват да направят дисонансите да работят. Тази според мен го прави.
Миглена Николчина: Дисонанс или не, нека си призная, че на три пъти започвах играта, защото началото е толкова ужасяващо, че нямах сили да продължа. Внедряват те в този много красив, много парижки мизансцен на границата на XIX и XX век, сред елегантни хора, цветя, изискани жестове, изпълнени с нежност реплики… докато се стигне до момент, в който става ясно, че всяка година всички, които са достигнали до все по-ниска възраст, биват изтривани. Това е годината, в която изтриват достигналите 34 години, следват 33-годишните. Прекрасното момиче, преплело ръце с прекрасно момче, се разпилява като подети от вятъра листенца. Денят е меланхолно естетизиран празник сбогуване на оставащите с изтриваните. „Гомаж“ – аз я играх на френски тази игра.
Северина Станкева: То и на английски е оставено „гомаж“ (gommage – букв. „изтриване, заличаване“).
Миглена Николчина: Играх я на френски, защото е френска игра. Така. Девойката е една година по-голяма от него и я изтриват. И множеството нейни връстници се разнасят като облак. Непоносимо. За мен загубата, за която става дума в тази игра и която е нейният най-осезаем аспект, не е свързана с личната драма, а с цивилизационната. Играта е за гибелта на Париж, на Френското просвещение, на великото френско изкуство с неговите институции, на френската цивилизованост, на френската естетизация на любовта, общуването, живеенето. Дали това е замисъл, дали е преднамерено, или се е получило като страничен ефект от абсурдния сюжет, не мога кажа. От интервютата със създателите, които гледах, не може да се разбере. Подсмихват се и не казват.
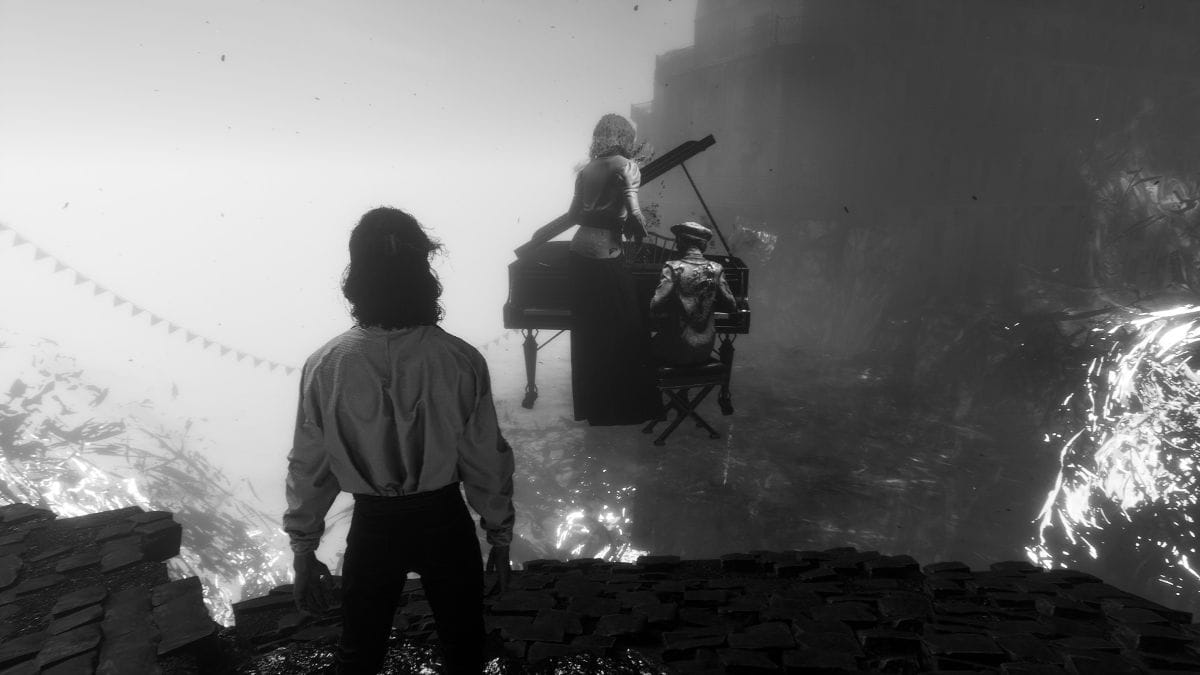
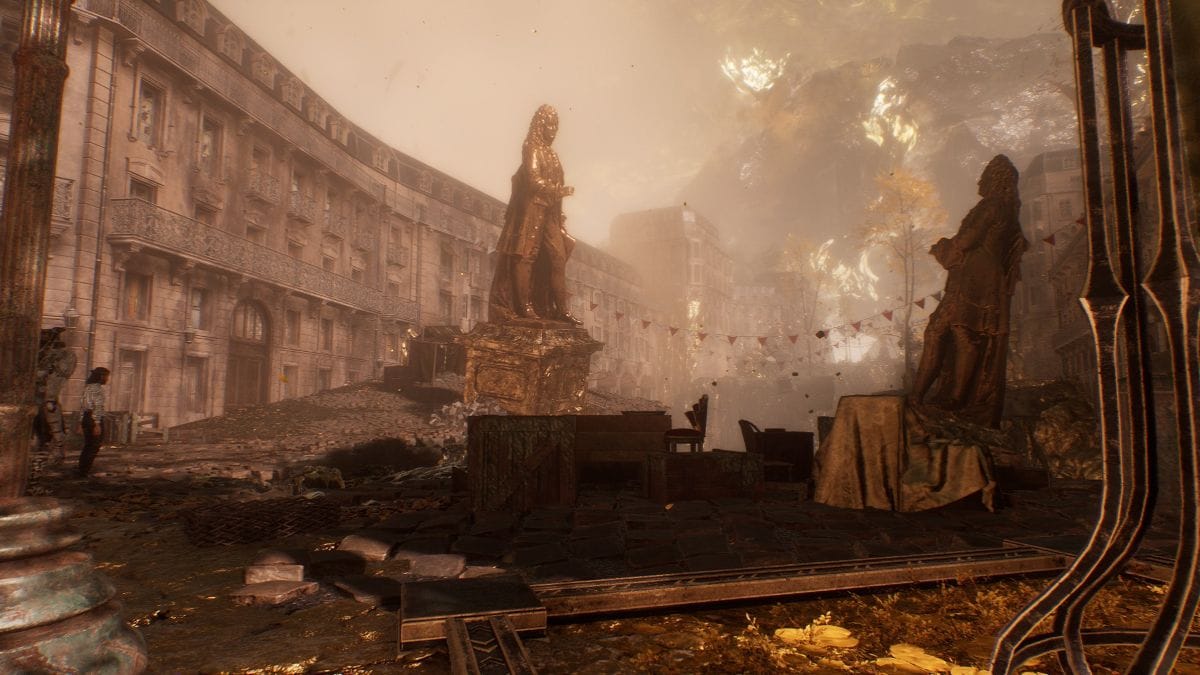
Кадри от „Светлосянка“
Да започнем с първата загадка. Трагедията, която се е случила – пожар в дома на семейство художници, при който синът Версо загива, предизвиквайки лавина от фантастични последици, – е през 1905 г. Защо точно тази година? Какво да мислим за главоблъсканицата с надгробния камък на Версо, който се появява в единия от финалите с дата на смъртта му 33 декември 1905 г.? Връзката с цифрите в заглавието на играта не ми казва нищо, освен ако не си спомним Данте с неговото 3 х 3 = 9 – Беатриче е деветка… По-съществена ми се струва самата преднамереност, с която ни подхвърлят една несъществуваща дата тъкмо във финала, който се предполага да е връщане в реалността.
Във всеки случай 1905-та е важна, преломна година, с която всъщност започва XX век. Тогава излиза частната теория на относителността на Айнщайн. Тя изключително драматично се преживява от хората на изкуството – и във Франция, и извън нея. Относителността на времето се превръща в обсесия, която поражда всевъзможни експерименти – например с романната форма у Джойс, Томас Ман, Вирджиния Улф и пр. В играта виждаме заиграване с времето на композиционно ниво, то тече по различен начин в „света на картината“ и „света отвън“. И това е само един от аспектите.
Във форумите открих нещо, което до този момент не бях отчитала. През 1905 г. във Франция се прокарва закон, който разделя религията от държавата и се обявява свобода на вероизповеданията. Ако приемем сериозно такава връзка, може да забележим липсата на катедралата „Нотр Дам“. Да не би пък тя да е изгоряла? Айфеловата кула я има, макар и килната, но сред множеството руини не видях никъде останки от „Нотр Дам“… Така че ето още една загадка.
Какво друго се случва през 1905 г.? Троцки издава своята книга „1905“. Тя е за Първата руска революция, която се случва тогава. Не смятам, че създателите на играта са мислили за тази революция, но и тя, и книгата са знак за това какво предстои. През 1905 г. умира Жул Верн и излизат два негови романа – единият, докато е все още жив, който се казва „Завладяването на морето“, и другият – „Фарът на края на света“. Не знам дали са имали предвид Жул Верн, но и фар, и завладяване на морето има.
Това, което ще изтъкна е, че през 1905-та се състои първата изложба на фовизма. Течението съществува за кратко, но се смята за повратна точка в историята на живописта. С него се слага край на предишните иновативни течения, каквито са импресионизмът и постимпресионизмът (Внимание! Името на бащата на семейството художници в играта е Реноар.) и се влиза в ера на множество „изми“, сред които – като тежко визуално присъствие в тази игра – ще спомена, освен фовизма, и сюрреализма.
Накратко, част от трагедията се отнася според мен до едно драматично преобръщане в историята на изкуството. Играта пласт върху пласт наслагва сякаш с блажни бои тази история, ние се движим в нея – и в драмата на нейния край, който е край на Париж като световна столица на изкуството и цивилизацията.
(Следва продължение.)
В рубриката „Игромислие“ публикуваме разговори, в които се срещат, съпоставят и противопоставят различни гледни точки към многоизмерния, многожанров феномен на видеоигрите – не толкова като електронен спорт, колкото като нов синтез на изкуствата и като ново поле на общуване и социалност.
2026-07-14 Chaos AD
Post Syndicated from Vasil Kolev original https://vasil.ludost.net/blog/?p=3529
Снощи отидох на концерт на братятя Кавалера, които изсвириха целия Chaos AD.
Беше в “Маймунарника”, който май никога не съм виждал толкова пълен. От техническа гледна точка събитието беше трагично – звукът на подгряващата група беше по-добре, по време на концерта соло китарата беше тиха и се губеше, и токът на сцената спря три пъти. Не мисля, че съм присъствал на подобна издънка, и е направо невероятно за подобен концерт.
Въпреки това, си беше забавно. Публиката беше пълна с хора от всякакви възрасти, от възрастта на моите деца до почти дядовци и радва, че и младото поколение беше дошло да чуе малко класическа музика.
Започнаха с Refuse/Resist (започващо вероятно с най-известния запис на пулс ever) и завършиха с cover на същото парче 🙂 Макс изглежда все още има глас, въпреки напредналите годинки, бяха довели буквално едно дете (Игор Амадеус, синът на Макс) на бас, имаха приличен китарист, и Игор Кавалера беше там като основната причина да бъдат чути (и слава богу не му бяха объркали много звука на барабаните, за да се чуе наистина както трябва). Направиха едно страхотно изпълнение на Kaiowas, което май беше най-добре получилата се песен на концерта.
Welcome to our live show!
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=VNz8l0pOhaA
Building Service Topology at Scale: Architecture, Challenges, and Lessons Learned
Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/building-service-topology-at-scale-architecture-challenges-and-lessons-learned-f4b792f3f0d8
By Parth Jain, Rakesh Sukumar, Yingwu Zhao, Renzo Sanchez-Silva & Nathan Fisher
A deep dive into the engineering challenges of building a real-time service dependency map at Netflix scale: from streaming architectures and distributed aggregation pipelines to time-travel queries and the methodology that made it work.
Introduction
In our first post, we introduced the problem: engineers at Netflix needed a unified, real-time view of service dependencies to troubleshoot faster, understand blast radius, and navigate our distributed architecture. We described our multi-source approach, combining eBPF network flows, IPC metrics, and distributed tracing into physically separate graph layers that can be queried independently or merged into a comprehensive view.
That post explained what we built and why. This post is about how, the engineering reality of building this system at Netflix scale.
Here’s the truth: the first version worked perfectly… in our local environment. Production was a different story. Kafka consumers fell behind. Instances ran out of memory. Some nodes received 100x the traffic of others. Garbage collection pauses consumed more CPU than actual business logic.
What you’ll learn in this post isn’t a success story, it’s a learning journey. We’ll walk through the architecture decisions that enabled scale, the production challenges that tested those decisions, the optimization methodology that guided us through, and the lessons that apply to any distributed system. Along the way, we’ll share the innovations that made it possible to process millions of flow records per second, reconstruct topology at any point in time, and provide sub-second query responses, all while maintaining near real-time freshness.
Architecture Deep-Dive: Building for Streaming and Scale
Streaming-First: Why Real-Time Matters
Traditional service topology systems use batch processing, aggregating data hourly or daily, then storing complete snapshots. This approach works at a modest scale but has a fundamental problem: by the time you see the data, it’s already old. During a production incident at 3am, an hour-old dependency map is archaeology, not observability.
Our key architectural decision was to build streaming-first. Instead of batch jobs that process historical data, we continuously ingest flow records from multi-region Kafka streams and IPC metrics as Server-Sent Events, process them through reactive pipelines with backpressure handling, and provide near real-time topology updates, typically within tens of minutes, compared to the hours-old or day-old data that batch processing approaches provide.
This wasn’t just about freshness, it was essential for our use cases. Live events can’t wait for the next hourly batch. Incident response needs current data. Change validation requires seeing immediate impact. The architecture had to support continuous updates while handling massive scale without falling behind.
How Backpressure Enables Real-Time Processing
The streaming approach created new challenges, but also required solving a fundamental problem: how do you process millions of flow records per second in real-time without losing data when downstream systems slow down?
Traditional approaches fall short at our scale:
- Unbounded queues: Simple but dangerous. Keep buffering until you run out of memory, then the instance crashes.
- Drop-based flow control: Discard data when buffers fill. Fast, but now your topology is incomplete, you’ve lost connection information.
- Batch processing: Process everything, but hours later. By then, the incident is over (or worse, still happening with stale data).
We needed something different: the ability to slow down gracefully under load without losing data. This is where reactive streams with backpressure became essential.
Here’s how it works: when Stage 3 can’t write to the graph database fast enough, it signals Stage 2 to slow down. Stage 2 signals Stage 1. Stage 1 signals the Kafka consumer to pause. The data waits in Kafka until downstream capacity returns.

Backpressure propagates naturally through the entire system. When any stage becomes overwhelmed from traffic spikes, GC pauses, or external slowdowns, the pipeline automatically slows to a sustainable rate. No data is lost in most cases, no instances crash, the system degrades gracefully.
This is what enables “real-time” at our scale. During normal operation, we process with minimal latency. During load spikes or temporary slowdowns, we slow down rather than fall over. The data still gets processed, just a few seconds or minutes later instead of immediately. For topology updates, this trade-off is acceptable: slightly delayed real-time updates are vastly better than hour-old batch data or incomplete topology from dropped records.
The cost of this approach is complexity. Reactive streams are harder to reason about compared to traditional synchronous blocking models (we’ll discuss this more in the challenges section). But at Netflix scale, backpressure isn’t optional, it’s the mechanism that keeps the system running reliably under production load.
Multi-Layer Architecture: Physical Separation for Independent Optimization
As we covered in our first post, our multi-source approach uses three physically separate topology layers with different storage optimized for each:
- Network Layer: eBPF flow logs in graph database partition, comprehensive coverage but lacks application context
- IPC Layer: Application metrics in a different graph database isolated from the one for Network Layer, rich endpoint details but only instrumented services
- Tracing Layer: Distributed traces in columnar storage (Parquet), actual request paths but sampled.(We cover the tracing layer and its integration in our next post).
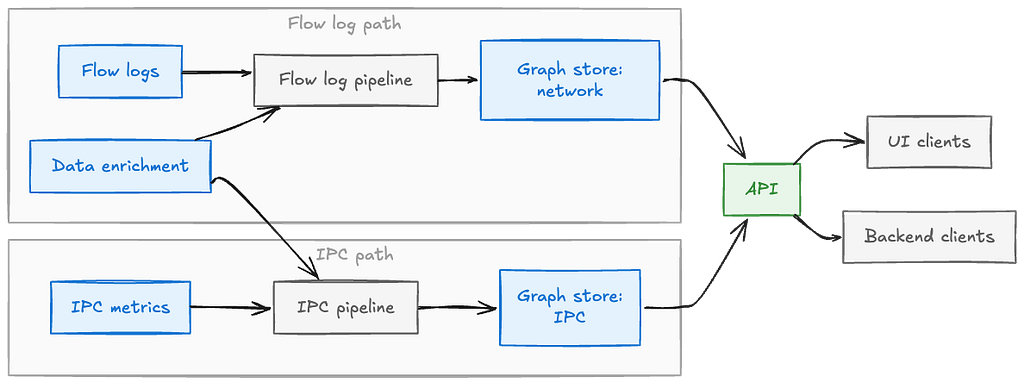
Physical storage isolation enables independent optimization, each layer has different throughput, query patterns, and evolution timelines. At query time, we execute parallel queries across relevant storage systems and merge results, providing unified views with sub-second latency while maintaining flexibility to evolve each layer independently.
The Three-Stage Distributed Aggregation Pipeline
The heart of the network layer ingestion is a three-stage distributed pipeline. This architecture solves a fundamental challenge with network flow logs: they only show individual network hops, not the true application-level connections we need to build a useful topology.
The Core Problem: Network Intermediaries
In cloud environments, traffic between applications rarely flows directly, it traverses intermediate network components like load balancers, NAT gateways, API gateways, and proxies. Network flow logs show individual hops: App A → Load Balancer and Load Balancer → App B appear as separate flows. But what engineers need is the logical dependency: App A → App B. Without resolving these intermediaries, our topology would be cluttered with infrastructure components rather than showing the service-to-service relationships that matter for troubleshooting.
The three-stage pipeline solves this:
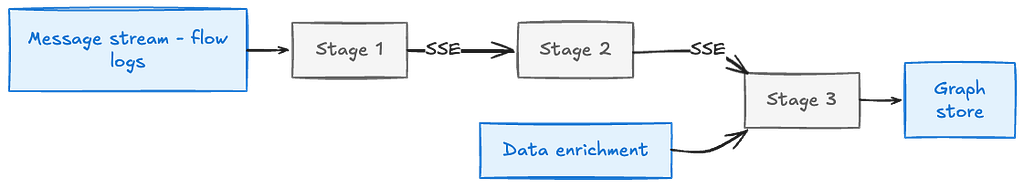
Stage 1: Initial Aggregation (FlowLog Ingestion Service)
Multi-Region Kafka (4 regions)
  → Filter invalid flow logs
  → 5-minute time-window batching
  → Create initial aggregators per window
  → Distribute via consistent hashing
  → Stream to Stage 2 via SSE
Stage 1 consumes flow logs from multi-region Kafka, filters invalid records, batches them into 5-minute time windows, and creates initial aggregator objects. At this stage, we’re still working with raw network hops, identifying which flows involve intermediaries but not yet resolving them. Aggregators stream to Stage 2 for resolution.
Stage 2: Network Intermediary Resolution Layer (Intermediate GraphEntity Ingestion Service)
Stage 1 Aggregators (via SSE streams)
  → Group flows by intermediary (load balancer, NAT gateway, proxy, etc.)
  → Identify pairs: (Source → Intermediary) + (Intermediary → Destination)
  → Resolve to direct edges: Source → Destination
  → Track which intermediaries were traversed
  → Aggregate metrics across both hops
  → Re-distribute via consistent hashing
  → Stream to Stage 3 via SSE
This is the key step. Stage 2 performs graph resolution:
- Collect flows by intermediary: Group aggregators where an intermediary is either source or destination, creating maps of flows going TO intermediaries (Source → Intermediary) and FROM intermediaries (Intermediary → Destination)
- Resolve direct edges: For each intermediary, join its incoming and outgoing flows to create direct application edges (App A → App B), combining metrics from both hops
- Result: Clean application-level topology showing App A → App B instead of App A → Load Balancer → App B
This resolution happens at aggregation time, not query time, with resolved edges flowing to Stage 3.
Why can’t we do this in a single stage? The fundamental issue is data locality. To resolve App A → Load Balancer → App B into App A → App B, we need both flows on the same instance to perform the join. But in Stage 1, flows are scattered across instances based on Kafka’s partitioning. Stage 2’s critical function is to redistribute aggregators by intermediary identifier, all flows involving “Load Balancer X” route to the same instance for resolution. This is the classic map-reduce pattern: Stage 1 maps, Stage 2 shuffles and reduces by intermediary, Stage 3 performs final aggregation.
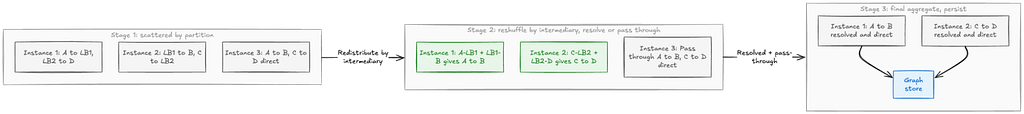
Stage 3: Final Aggregation and Enrichment (GraphEntity Ingestion Service)
Stage 2 Aggregators (via SSE streams)Flow
  → Final aggregation across time windows
  → Enrich with external data (query key-value stores)
  → Convert to graph entities
  → Persist to graph database (throttled writes)
Stage 3 performs final aggregation of resolved edges, enriches graph nodes with external data sources (application health, ownership, metadata), converts aggregators to concrete graph entities (nodes and edges with all properties populated), and persists them to the distributed graph database with controlled throttling to respect storage system limits.
Why Three Stages, Not Two?
We initially used two stages: aggregate in Stage 1, resolve and persist in Stage 2. This worked in testing but failed at production scale, Stage 2 became overwhelmed by data concentration.
The problem: intermediary resolution requires collecting ALL flows involving an intermediary on the same instance.As a result, the instances handling flow logs for popular applications and their intermediaries became ‘hot nodes’ due to significant data concentrationCompounding this, data enrichment (querying external stores for health and metadata) meant the busiest instances were also doing the most I/O.
The solution: split responsibilities into three stages. Stage 2 focuses purely on resolution and redistributes. Stage 3 handles enrichment and persistence. This graduated redistribution (distribute, resolve, distribute again), persist, spreads load across multiple instances and isolates compute-heavy resolution from I/O-heavy enrichment. Even when intermediaries see 100x typical traffic, no single instance becomes a bottleneck.
Why Server-Sent Events Instead of gRPC or Message Queues?
We initially used gRPC but it became a performance bottleneck, serialization overhead, connection pool management, and memory pressure for streaming responses consumed more CPU than business logic. Message queues added infrastructure complexity without benefit for our use case.
SSE proved ideal: lightweight HTTP-based protocol with minimal serialization, natural backpressure integration with reactive streams, and simpler connection model. The lesson: industry best practices like “use gRPC for service communication” don’t apply universally. For streaming large volumes of pre-aggregated data, lighter-weight alternatives may be more appropriate. Measure, don’t assume.
Why IPC Doesn’t Need Three Stages
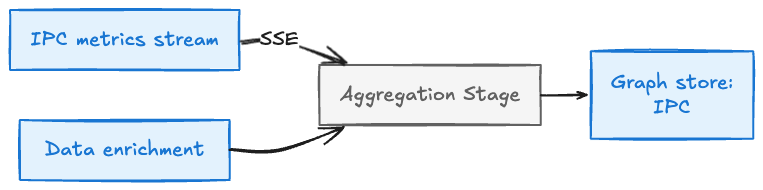
The IPC layer uses single-stage aggregation because: (1) IPC metrics are already at application level, no intermediaries to resolve, and (2) data is partitioned correctly from the start — each node receives all IPC metrics for its assigned applications via consistent hashing, eliminating the need for redistribution. This highlights a key principle: data partitioning strategy determines processing architecture. When data arrives with the right partitioning, you can aggregate directly; when it doesn’t (like network flows requiring intermediary resolution), you need shuffle/redistribution stages.
Dynamic Load Distribution: How Hashing Works with Auto-Scaling
How do we decide which instance receives which aggregator when our Auto Scaling Groups dynamically add or remove instances? Traditional approaches assume static clusters requiring explicit rebalancing, coordination services, or manual data movement when cluster size changes.
Our Approach: Dynamic Consistent Hashing
We use consistent hashing with dynamic instance discovery from our service registry. Each instance queries the registry to get the current list of healthy ASG instances, maintains them in sorted order (ensuring all instances have the same view), and uses this list for the hash function findOwnerInstance(aggregator.primaryKey). When ASG scales up or down, the hash function naturally redistributes aggregators based on the updated instance list, no explicit coordination needed.
The key insight: leverage existing infrastructure. Our service registry already tracks ASG membership for health checking. Using it as our source of truth gives us dynamic cluster membership for free. Consistent hashing provides stable partitioning (most aggregators stay on the same instance during membership changes), while the sorted list ensures consistency.
The Result
Load follows infrastructure automatically. During traffic spikes or live events, new instances immediately receive their share. During deployments, aggregators seamlessly shift to healthy instances. This pattern proved crucial for production stability, no manual intervention, no coordination protocol, just automatic rebalancing.
The V1 Journey: Major Challenges at Production Scale
Getting the initial version (V1) to production taught us that scale changes everything. What works in development breaks in production. Every assumption gets tested. And fixing one bottleneck reveals the next.
Challenge 1: Kafka Consumer Lag
The Problem: Our multi-region Kafka consumers started falling behind. Consumer lag grew from seconds to minutes, then hours. Flow logs were arriving faster than we could process them. If this continued, we’d never catch up, and our “real-time” topology would become increasingly stale.
Investigation: We instrumented Kafka consumer metrics heavily. Key findings:
- Kafka had fewer partitions than optimal for our consumer group size
- Each fetch operation retrieved relatively few records
- Network socket buffers weren’t right-sized for our throughput
- Cross-region read latency added overhead
Solutions Applied:
- Increased Kafka partitions: More partitions enabled more parallel consumers in our consumer group, distributing load across more instances.
- Tuned fetch parameters: Increased records per fetch operation, reducing the number of network round-trips. This trades off per-message latency (we fetch larger batches) for throughput (more records processed per second).
- Increased socket receive buffer size: Ensured network buffers never limited fetch operations. At our scale, default buffer sizes were too small.
Results: Throughput improved significantly, and lag reduced to acceptable levels, typically under a minute even during peak traffic.
Lesson: At scale, you can’t optimize in isolation. Fixing Kafka lag revealed the next bottleneck: our instances themselves couldn’t keep up with the higher ingest rate. The pipeline moved faster, which exposed downstream capacity problems.
Challenge 2: Hot Nodes and Data Amplification
The Problem: This was the most severe production issue we faced. Some instances in our Auto Scaling Group were receiving 100x more traffic than others. Memory usage spiked. Garbage collection pauses became frequent and long. More CPU time was spent in GC than in business logic. Eventually, hot instances would go DOWN, triggering cascading failures as their load redistributed to other instances.
Root Cause Investigation:
Flow logs for popular services dominate traffic volume. A service like our authentication layer or recommendation API is called by hundreds of other services, generating orders of magnitude more flow records than typical services.
Our initial architecture used consistent hashing to determine which instance owned aggregation for each destination service. All flow logs for a given destination are routed to the same instance, the “owner” for that destination. This design seemed reasonable: group related data for efficient aggregation.
But popular destinations created hot nodes. One instance might own authentication services, another might own a rarely-used backend service. The load distribution was wildly uneven, some instances handled 100x the flow records of others.
Worse, data amplification occurred during redistribution. Consider a service called by 100 upstream services across 10 instances. All 10 instances receive flow logs for that destination (because they all have local clients calling it). When they route aggregators to the owner instance, that instance receives 10 separate aggregators it must merge. The data volume multiplied during shuffling.
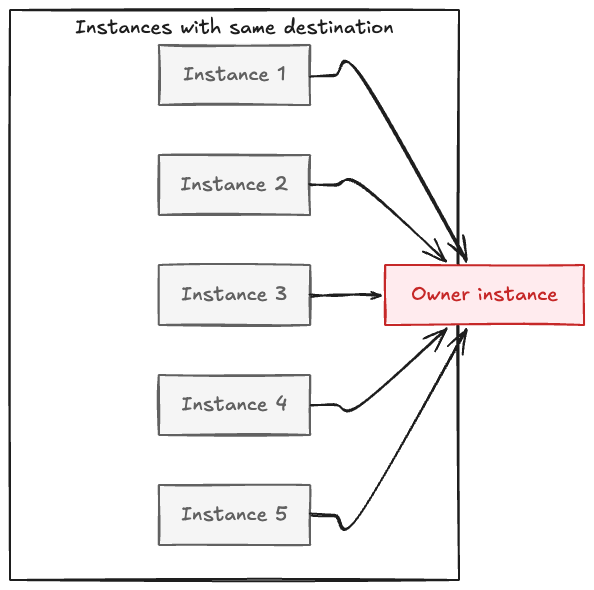
We profiled extensively using async-profiler and heap dump analysis. The results were clear: hot instances spent most of their CPU on garbage collection, trying to manage the rapid allocation and deallocation of aggregator objects as flow logs poured in faster than they could be processed. Memory pressure led to GC thrashing, which consumed CPU, which slowed processing, which increased memory pressure, a vicious cycle.
Solution: The Three-Stage Pipeline’s Dual Benefits
The three-stage pipeline we described earlier, designed primarily for proxy resolution, turned out to be exactly what we needed to solve the hot nodes problem as well. Here’s why:
Stage 1 performs initial aggregation locally before any distribution. Instead of sending every flow log to a remote instance immediately. Each instance performs online aggregation of raw flow logs into time-windowed aggregators (over 5-minute periods) directly in memory; this allows the raw flow to be discarded and garbage collected quickly, significantly reducing memory pressure, and ensures only the aggregation results are transferred across the network to downstream stages.
Stage 2 focuses on proxy resolution but also provides intermediate redistribution. Aggregators from Stage 1 distribute via consistent hashing to Stage 2 instances. Now we’re moving compressed aggregators, not individual flow logs. After resolution, Stage 2 redistributes resolved edges again to Stage 3, providing a second hashing operation that further spreads load.
Stage 3 receives resolved aggregators that have been compressed twice and distributed twice. Even for extremely popular services, load has been spread across enough distribution points that no single instance becomes overwhelmed.
The key insight: architectural decisions driven by one requirement (proxy resolution) often solve other problems (load distribution) as beneficial side effects. The three-stage pipeline with graduated redistribution achieves both goals, it resolves proxies to show clean application-level topology AND prevents hot nodes by spreading load across multiple distribution points.
Switching from gRPC to SSE
As described earlier, this challenge also revealed that gRPC wasn’t the right protocol for inter-stage communication at our scale. We replaced gRPC with Server-Sent Events, dramatically reducing resource consumption on both sender and receiver sides.
Results:
- CPU usage became evenly distributed across instances, no more hot nodes with 10x the load of others
- Network bandwidth usage dropped significantly due to better aggregation and lighter-weight protocol
- Memory pressure decreased as we reduced the object allocation rate
- The system scaled gracefully with Auto Scaling Group changes
Lesson: Technology choices must match your specific use case. gRPC is excellent for request-response RPC patterns. For streaming large volumes of aggregated data in a pipeline, lighter-weight alternatives can be more appropriate. Let measurements guide the decision, not industry hype or existing team expertise.
Challenge 3: Memory and Garbage Collection
The Problem: Even after fixing hot nodes, we still saw high heap usage, frequent garbage collection pauses, and instances occasionally going DOWN. GC logs showed pauses consuming significant CPU time, in some cases, more than our business logic.
Root Cause: Multiple factors contributed: objects accumulating in heap while waiting for 5-minute aggregation windows to complete, unnecessary conversions between different object types as data flowed through stages, and immutability overhead, following Scala best practices, we used immutable data structures for aggregators, but every update created new objects, overwhelming the garbage collector at millions of records per second.
Investigation: Heap dumps and GC logs revealed flow log objects retained beyond their useful lifetime, unnecessary intermediate conversion objects, and constant creation/disposal of immutable aggregator versions. Minor GCs occurred every few seconds, major GCs took hundreds of milliseconds, the JVM spent more time on garbage collection than business logic.
Solutions Applied:
- Faster processing: Process flow logs immediately, aggregate quickly, release references. Optimized Pekko stream stages to minimize object lifetime.
- Eliminate unnecessary conversions: Route aggregators directly between stages instead of converting to intermediate types.
- Mutable structures on hotpath: This was controversial, Scala best practices emphasize immutability. But at our scale, immutability created too many objects. We pragmatically chose mutable aggregators on the hotpath (immutability elsewhere), prioritizing performance over convention. Switching to mutable aggregators reduced heap allocation by over 50% and cut GC pause time significantly, though it required more careful code review.
- Tuned time windows: Balanced data freshness against memory pressure.
Results:
- Heap usage decreased substantially
- GC pauses reduced to acceptable levels (tens of milliseconds instead of hundreds)
- CPU freed up for business logic instead of garbage collection
- Instance stability improved, no more instances going DOWN due to memory issues
Lesson: “Best practices” are starting points, not absolute rules. At unique scale, you may need to diverge from conventions. But do it deliberately, with measurement justifying the decision, and with awareness of the trade-offs. Don’t abandon immutability everywhere, just where performance data proves it’s necessary.
Challenge 4: Reactive Streams Complexity
The Problem: Our Pekko Streams pipelines would stall unexpectedly. Backpressure propagation didn’t work as expected. We struggled to debug why certain streams would stop processing without obvious errors. The reactive programming mental model, with its emphasis on async boundaries, backpressure, and demand-driven processing, proved harder to master than anticipated.
What We Learned:
Reactive streams with backpressure are powerful tools for building systems that handle load spikes gracefully. When downstream consumers slow down (due to temporary load, GC pauses, or external system slowdowns), backpressure allows upstream producers to slow down rather than overflow buffers or drop data.
But this power comes with complexity:
- Non-intuitive behavior: Traditional imperative code flows top-to-bottom. Reactive streams are demand-driven, downstream consumers pull from upstream producers. This inversion of control isn’t intuitive.
- Async boundaries: The .async operator in Pekko Streams creates a boundary where processing moves to a different thread. This can improve parallelism but also introduces complexity around buffer sizing, demand signaling, and error propagation. We initially misunderstood when to use .async and ended up with over-parallelized streams that created more overhead than benefit.
- Debugging difficulty: When a stream stalls, there’s no stack trace pointing to the problem. You must understand the internal mechanics, demand signals, buffer states, materializer state to diagnose issues.
Our Approach:
- Deep learning investment: We invested significant time in understanding reactive streams concepts deeply. Reading documentation, experimenting with small examples, and building team expertise.
- Simplified patterns: Where possible, we simplified our stream graphs. Complex branching and merging patterns are powerful but hard to debug. We preferred linear flows with clear stage boundaries.
- Better monitoring: We added metrics at stream boundaries, tracking buffer sizes, element throughput, backpressure events. Visibility into stream internals helped diagnose issues.
- Team education: We documented our learnings, shared patterns that worked, and built institutional knowledge about reactive streams.
Lesson: Powerful abstractions require investment. Don’t assume you understand a framework without validation. Build your mental model deliberately, test it with experiments, and be humble about your understanding. Reactive streams are worth mastering for systems that need to handle load gracefully, but expect a learning curve.
V2 Evolution: Continuous Refinement
V1 got us to production. The major architectural challenges like Kafka lag, hot nodes, memory pressure, were solved. But production at full scale revealed new optimization opportunities. V2 represents the continuous refinement that turns a working system into a production-ready system.
Challenge 5: Persistent Heap Pressure
The Problem: Despite V1 optimizations, we still observed higher-than-desired heap usage. GC metrics improved but weren’t optimal. Memory profiling showed room for improvement.
Root Cause: Deeper analysis revealed we were still doing unnecessary object conversions between stages. We’d convert aggregators to full graph entities (with all properties populated) before routing to the next stage, even though the next stage just needed the compressed aggregator state.
Solution: Architectural change to route aggregators directly through all stages, only converting to final graph entities at Stage 3 immediately before persistence. This eliminated two intermediate conversion steps and the associated object allocation.
Result: Heap usage dropped further, GC pauses became even less frequent, and memory headroom improved.
Challenge 6: Serialization Complexity
The Problem: Custom serialization logic for SSE messages caused occasional erratic errors that were hard to reproduce and debug. Different parts of the codebase used inconsistent serialization approaches.
Solution: Standardized on JSON encoding throughout the pipeline. While slightly less efficient than binary serialization, JSON’s human readability made debugging far easier, and the overhead was negligible compared to other operations. Consistency eliminated an entire class of bugs.
Result: Serialization-related errors disappeared. Debugging became easier because we could read SSE message contents directly.
Challenge 7: Stream Processing Inefficiencies
The Problem: Even after understanding reactive streams better, our Pekko configurations weren’t optimal. We had over-parallelized some stages and under-parallelized others. The .async boundaries weren’t placed optimally.
Solution: Through continued profiling and experimentation, we tuned parallelism parameters, adjusted buffer sizes, and refined async boundary placement. We added monitoring at stream boundaries to identify bottlenecks.
Result: Throughput improvements and more consistent processing latency.
Challenge 8: Uneven Graph Database Throughput
The Problem: Write distribution to our graph database wasn’t even. Some partitions received heavy write traffic while others sat idle. This caused throttling to kick in unevenly and limited overall write throughput.
Solution: Implemented batching of aggregators before writing to the graph database and improved distribution logic across partitions. Rather than writing each aggregator immediately, we batch them and write multiple entities in coordinated operations.
Result: More consistent write throughput and better utilization of database capacity.
Challenge 9: Data Enrichment at Aggregation Time
Beyond the core topology graph, we needed to enrich nodes with additional context. At Stage 3, before persisting graph entities, we integrate enrichment data from external sources, application health status, ownership information, and other metadata. Performing this enrichment at aggregation time rather than at query time avoids the performance overhead of post-query joins and ensures every topology node has full context when queried.
Pattern Recognition
Each V2 challenge followed the same pattern: production revealed an assumption, profiling identified the root cause, targeted fixes improved specific metrics. Measure, hypothesize, validate, iterate. This is how you build at scale, not by getting everything right upfront, but by continuous learning and improvement.
Time Travel: Continuous Topology Reconstruction
One of the most powerful capabilities we built enables querying historical topology: “What did the call graph look like when this incident happened?” This time-travel feature required solving an interesting architectural challenge, how to efficiently store and reconstruct topology across time.
The Problem
Engineers need to answer temporal questions: What did the topology look like during an incident? How have dependencies evolved? Traditional approaches, full snapshots or event sourcing — either have exponential storage costs or require slow log replay.
Our Approach: Time-Windowed Aggregators with Mutation Tracking
We combine two mechanisms:
1. Time-Windowed Aggregator Snapshots: Every aggregator stores startTs and endTs timestamps for its 5-minute window. These immutable aggregators persist in the graph database keyed by (entity_id, timestamp), providing checkpoint states every 5 minutes.
2. Property-Level Mutation Tracking: The graph database maintains mutation history at the property level, storing only changed properties with timestamps. This is much more efficient than full entity copies and provides sub-window precision beyond the 5-minute aggregation boundaries.
3. Query-Time Reconstruction: When querying historical topology, we query the mutation history API for the time range, retrieve all mutations, and reconstruct topology state by applying mutations in order.
This approach provides efficient storage (compressed aggregator states + sparse property mutations), fast retrieval (indexed mutation history, no log replay), and flexible analysis (arbitrary time ranges without pre-computing all possibilities).
Query-Time Re-Aggregation: We can further aggregate historical data at query time using the same aggregator classes from ingestion. This enables arbitrary groupby dimensions (availability tier, business domain, deployment cluster) that weren’t pre-computed, allowing exploratory analysis without exploding storage costs.
Lessons for Distributed Systems
While these challenges were specific to service topology, the lessons apply broadly to distributed systems at scale.
Scale Changes Everything
What works at 100 requests per second fails at 100,000 requests per second. The change isn’t linear, it’s qualitative. Approaches that are fine at modest scale hit fundamental walls at extreme scale.
Examples from our journey: immutable data structures create GC pressure at millions of allocations per second; single-stage aggregation fails catastrophically with power-law traffic distribution; standard gRPC becomes heavyweight for streaming aggregation at volume.
The lesson: be willing to break conventional wisdom when scale justifies it. But do it based on measurement, not speculation.
Optimize One Bottleneck at a Time
Distributed systems have cascading bottlenecks. Fix Kafka lag, and you discover hot node issues. Fix hot nodes, and you discover GC problems. Fix GC, and you discover serialization inefficiencies.
This isn’t failure, it’s the nature of complex systems. Each optimization raises throughput, which stresses the next weakest point. The approach: prioritize based on impact, fix the current bottleneck thoroughly with measurement confirming resolution, then move to the next one. Optimization at scale is continuous, not one-time.
Distribution Is Key to Scale
Single aggregation points are inevitable bottlenecks. Consistent hashing distributes load but doesn’t prevent concentration when data itself is unevenly distributed (power-law distributions like ours).
Our three-stage pipeline with graduated redistribution solved this. Load spreads across multiple distribution points at each stage. Even with highly skewed data, no single instance becomes overwhelmed. The general principle: use multi-stage processing with redistribution at each stage when dealing with skewed data at scale.
Current State and Impact
Service Topology operates in production today, processing flow logs, ipc metrics and traces from multiple regions and serving queries with sub-second latency. Teams across Netflix use it daily for incident investigation, blast radius analysis, dependency understanding, and production change management. The system has become essential infrastructure for maintaining reliability at scale.
Conclusion
Service Topology at Netflix represents a journey through building distributed systems at scale. We started with engineers struggling to understand dependencies across scattered tools. We built a multi-layer architecture using streaming aggregation, network intermediary resolution, and time-travel capabilities. And we learned that optimization at scale is continuous, measure, iterate, validate, repeat.
The challenges we faced, Kafka lag, hot nodes, memory pressure, required breaking conventional wisdom when data justified it. Each fix revealed the next bottleneck. But that iterative process, guided by constant measurement, is what makes systems work at extreme scale.
In our next post, we’ll explore the tracing layer integration, unified querying across heterogeneous storage, and how all three layers combine to provide comprehensive topology visibility.
Acknowledgements
Service Topology was built by Parth Jain, Rakesh Sukumar, Yingwu Zhao, Renzo Sanchez-Silva, and Nathan Fisher.
Special thanks to the many engineers across Netflix who made this possible — the Observability team who built the broader system, the graph database platform team who provided the storage foundation, and the Platform Modernization Engineering, and Live teams who provided invaluable feedback and use cases throughout development.

Building Service Topology at Scale: Architecture, Challenges, and Lessons Learned was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
The Hidden Cost of Optimization Culture
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/IfByW89WT68
Eliminating Java cold starts with AWS Lambda Managed Instances
Post Syndicated from Jay Colodner original https://aws.amazon.com/blogs/compute/eliminating-java-cold-starts-with-aws-lambda-managed-instances/
A single cold start can push your Java Lambda function’s response time from milliseconds to seconds, enough to violate your p99 SLA, timeout a downstream service, and page your on-call. The Java Virtual Machine (JVM) performs best in long-running processes. Its Just-In-Time (JIT) compiler progressively optimizes code over thousands of invocations. Standard serverless execution environments recycle before the JVM reaches peak performance. This creates a tradeoff for latency-sensitive applications between cold-start penalties and runtime optimizations. For production services with p99 service level agreement (SLA) requirements, a single 14-second cold start spike can violate response time guarantees. It triggers downstream timeouts and degrades customer experience.
AWS Lambda Managed Instances changes this equation. As a capability of AWS Lambda, Managed Instances runs your functions on managed Amazon Elastic Compute Cloud (Amazon EC2) instances in your account and maintains JVM persistence across invocations. Connection pools, class hierarchies, and heap state persist across thousands of requests. This allows the JIT C2 compiler to complete optimizations like method inlining, escape analysis, and loop unrolling. The result: 18 to 30% better median latency and 3 to 30x better tail latency compared to Standard Lambda, as the benchmarks in this post demonstrate.
This post benchmarks four Java deployment modes across three workload types using 240,000 requests. The modes compared are Standard Lambda, AWS Lambda SnapStart, GraalVM Native Image, and Lambda Managed Instances. The workload types are CPU-bound, I/O + computation, and I/O-bound. This post presents benchmark results demonstrating Managed Instances delivering 30% better median latency and removing multi-second cold-start spikes on CPU-bound work after JIT warmup. It explains why these gains occur, maps each deployment mode to specific traffic patterns and cold-start tolerance requirements, and provides a decision framework for selecting the right approach for your workload.
Benchmarking setup
The benchmark runs all four deployment modes with identical Spring Boot 4.0.6 applications on Java 25 and AWS SDK v2. This configuration verifies fair comparison across modes. We tested three workloads: UC1 (PDF generation, CPU-bound), UC2 (data aggregation, I/O + computation), and UC3 (API orchestration, I/O-bound). The benchmark sends 240,000 requests using Artillery load testing at 33 RPS. Standard Lambda, SnapStart, and Native Lambda use 1024 MB (1 vCPU). Managed Instances uses c7i.xlarge instances with 2048 MB memory. Concurrency is tuned per workload (UC1=3, UC2=5, UC3=10) based on load testing to avoid thread contention. The benchmark measures p50, p99, and maximum latency across 10 runs of 2,000 requests each, with 5-minute cool-down between runs. The benchmark tracks JIT compilation metrics via Amazon CloudWatch Embedded Metrics Format. You can validate these results against Amazon API Gateway access logs, which confirm a <0.1% error rate. The GitHub repository contains complete source code, AWS Serverless Application Model (AWS SAM) templates, load scripts, and raw data. Performance claims in this post reference data from this benchmark methodology.
Figure 1 presents the architecture for all four deployment modes running in parallel against shared backend services.
To reproduce these benchmarks or deploy the sample applications, refer to the GitHub repository. The repository contains complete SAM templates, Artillery load configurations, deployment instructions, and cleanup commands. This post focuses on benchmark results and analysis. The benchmark used the following tools and services:
- An AWS account with permissions to create Lambda functions, Amazon DynamoDB tables, Amazon Simple Storage Service (Amazon S3) buckets, Amazon Simple Notification Service (Amazon SNS) topics, and Amazon Simple Queue Service (Amazon SQS) queues
- Java 25 (Amazon Corretto recommended).
- Maven 3.9+.
- AWS SAM CLI v1.155 or later.
- Docker (for GraalVM native image builds) or alternative.
- Artillery for load testing.
- The GitHub repository with complete source code and SAM templates
Observing max latency
Managed Instances removes the extreme tail spikes characteristic of cold starts. Managed Instances delivers 27x faster maximum latency on CPU-bound workloads (UC1: 489 ms vs. 13,270 ms Standard). Mixed I/O + compute workloads see a 3x improvement (UC2: 3,644 ms vs. 11,174 ms Standard). I/O-bound workloads improve 30x (UC3: 309 ms vs. 9,237 ms Standard). We measured all results using the methodology described in Benchmarking setup.
The Standard Lambda 13-second maximum on UC1 represents a full cold start. That cold start includes JVM boot, Spring context initialization, Amazon DynamoDB client setup, and the first PDF render. SnapStart reduces this to under 3 seconds by restoring from a Firecracker microVM snapshot. However, the restore process plus re-initialization of resources that cannot be checkpointed (network connections, random number generators) still adds latency. GraalVM Native starts in under 2 seconds because the ahead-of-time (AOT) compiled binary skips JVM boot entirely. The Managed Instances maximum of 487 ms is not a cold start; it’s the slowest warm request across 20,000 invocations. For production SLAs, a 14-second cold start spike on Standard Lambda violates most requirements, while Managed Instances removes that spike entirely.
Observing median latency (p50)
Lambda Managed Instances delivered the lowest median latency across all three workloads. Results demonstrate 30% faster median latency on CPU-bound workloads (UC1: 97 ms vs. 139 ms Standard). Mixed I/O + compute achieves a 19% improvement (UC2: 184 ms vs. 228 ms Standard). I/O-bound workloads improve 18% (UC3: 76 ms vs. 93 ms Standard).
The improvement scales with CPU intensity because the JIT C2 compiler on persistent Managed Instances optimizes hot code paths that short-lived serverless environments never reach. On CPU-bound workloads (UC1), the JIT compiler has more opportunity to optimize tight loops in PDF rendering. On I/O-bound workloads (UC3), network latency to Amazon DynamoDB, Amazon SQS, and Amazon SNS dominates the request duration, so JIT optimization provides smaller gains.
Observing tail latency (p99)
Managed Instances showed even larger improvements at the tail of the latency distribution. The p99 improves 36% on CPU-bound workloads (UC1: 225 ms vs. 353 ms Standard). Mixed I/O + compute achieves a 41% improvement (UC2: 1,883 ms vs. 3,201 ms Standard). I/O-bound workloads improve 27% (UC3: 193 ms vs. 265 ms Standard).
UC2 showed the largest p99 improvement (41%) because data aggregation combines DynamoDB queries, returning hundreds of records with in-memory statistical computation and Amazon S3 uploads. Standard Lambda environments that haven’t fully warmed their JIT produce significantly slower responses at the tail. The persistent JIT optimization (-Xms512m -Xmx1408m) with G1 garbage collection (GC) and explicit heap sizing on Managed Instances both contribute to tighter tail latency distribution. For services with SLAs on p99 response time, this reliability improvement matters more than median performance. For workloads with significant heap pressure, tuning -XX:MaxGCPauseMillis and monitoring GC logs can further tighten tail latency.
Why Lambda Managed Instances is faster: JIT compilation
The JVM’s Just-In-Time compiler works in tiers. The C1 compiler performs initial compilation quickly with basic optimizations. The C2 compiler profiles execution over hundreds of invocations and then applies aggressive optimizations: method inlining (eliminating function call overhead), escape analysis (allocating objects on the stack instead of the heap), loop unrolling (reducing branch overhead), and vectorization (processing multiple data elements in a single CPU instruction).
The following table presents JIT warmup progression using java.lang.management.
CompilationMXBean emitted through Amazon CloudWatch Embedded Metrics Format. We collected this data from a 1,500-request sustained load test on UC1 (PDF generation):
| Phase | Invocation | Avg Latency | What’s Happening |
| First requests (application init) | 1 | ~2,400ms | JVM boot, spring context creation, SDK client setup |
| Early requests (C1 compiled) | 2-100 | ~145ms | C1 compiler active. App is functional, but not optimized |
| Steady state (C2 optimized) | 1000+ | ~38ms | C2 optimizations completed |
The first invocation includes one-time application start costs: class loading, Spring context initialization, and DynamoDB client construction. These costs are unrelated to JIT compilation and occur on any deployment mode.
Once C1 compilation stabilizes during early invocations, latency reaches approximately 145ms. This is the baseline compiled performance. Over the next several hundred invocations, the C2 compiler profiles hot code paths and applies optimizations. By invocation 1,000, latency drops to 38ms. This represents a 3.8x improvement from JIT optimization alone.
Standard Lambda environments typically recycle before C2 completes its optimization passes. On Managed Instances, concurrent requests share the same JVM. This accelerates JIT profiling: three concurrent requests generate three times the method invocation data for the C2 compiler to optimize. The C2 compiler profiles execution patterns across all concurrent requests. It identifies hot code paths faster and applies optimizations sooner than single-concurrency environments.
What this means: CPU-bound workloads see the largest gains (30% faster median latency on UC1) because the JIT compiler has more opportunity to optimize tight loops and method calls. I/O-bound workloads see smaller gains (18% faster on UC3) because network latency to DynamoDB, SQS, and SNS dominates request duration. The JIT compiler still optimizes your code, but the network time remains constant across all deployment modes.
Choosing the right mode
No single mode wins in every scenario. The right choice depends on your traffic pattern, cold-start tolerance, team expertise, and operational complexity budget.
Lambda Managed Instances is ideal for steady-state traffic patterns above 5 requests per second with low cold-start tolerance (p99 SLA under 500 ms). Best for workloads with predictable, sustained traffic that need low latency with zero cold starts. Managed Instances excels at CPU-bound workloads where JIT optimization compounds.
SnapStart works well for variable traffic patterns where cold-start reduction matters. Choose this as the default for Java Lambda functions. SnapStart reduces cold starts with minimal code changes (add CRaC priming). You have no additional infrastructure to manage. Works with the existing Lambda scaling model.
GraalVM Native Image works well for bursty traffic patterns with strict cold-start tolerance (sub-second cold starts required). Ideal if your team can invest in AOT compatibility (reflection configuration, build pipeline). This mode offers a smaller memory footprint. Requires testing for SDK compatibility.
Standard Lambda is the baseline for low-traffic or burst workloads where cold starts of 6-14 seconds are acceptable. Works well when invocation frequency is low enough that per-request billing is cheaper than fixed instance costs, or when operational simplicity is the top priority.
For example, if you run a Spring Boot API handling 100 requests per second with a 400 ms p99 SLA, Lambda Managed Instances reduces your p99 from 353 ms (cutting it close) to 225 ms (comfortable margin) and removes the multi-second cold start spikes that violate your SLA entirely.
| Dimension | Standard | SnapStart | Native | Managed Instances |
| Cold start | 6-14 s | 2-7 s | 800 ms – 2 s | None |
| Warm p50 (CPU-bound) | 139 ms | 127 ms | 107 ms | 97 ms |
| Tail latency | Worst | Better | Good | Fastest |
| Error rate | Low | Low | Higher (SDK compat) | Low |
| Operational complexity | Lowest | Low | High (build pipeline) | Medium (VPC, sizing) |
| Burst scaling | Fastest | Fastest | Fastest | Slower (capacity provider) |
| Migration effort | None | Low (add CRaC priming) | High (AOT compat, reflection configuration) | Medium (capacity provider, VPC, thread safety) |
| Memory efficiency | Good | Good |
Lowest (125-154 MB) |
Fixed per instance |
Lambda Managed Instances supports Graviton4 (arm64) instances, which offer approximately 20% better price-performance based on AWS published Graviton4 benchmarks. These benchmarks use x86_64 for consistency across all four modes (GraalVM native cross-compilation to arm64 adds complexity). The arm64 parallelization characteristics could shift the performance curves for longer-lived deployment modes like Managed Instances in ways worth exploring in a future post.
Cost considerations
Lambda Managed Instances uses instance-based pricing rather than per-invocation billing. For steady-state workloads above approximately 9 requests per second, the fixed instance cost is lower than equivalent Standard Lambda GB-second charges. You can use the official pricing calculator to compare Managed Instances and standard Lambda costs.
Try it with your runtime version
These benchmarks use Java 25 with Spring Boot 4.0.6. The GitHub repository also includes configurations for Java 21 with Spring Boot 3.x. The repository README walks you through deployment, load testing, and collecting your own metrics.
Conclusion
This post demonstrates how Lambda Managed Instances solves a fundamental Java-on-serverless mismatch. The JVM’s JIT compiler needs time to optimize hot code paths. Standard Lambda recycles environments before the JVM reaches peak optimization. Managed Instances keeps the JVM alive across invocations, allowing the C2 compiler to reach peak optimization. The benchmarks show the impact. In these benchmarks, Managed Instances delivered 18 to 30% faster p50 latency than Standard Lambda. Tail latency improved 27 to 41% at p99. Maximum response times dropped 3 to 30x on CPU-bound workloads. The 3.8x improvement from JIT optimization alone shows what’s possible when the runtime has time to complete its work.
For more information, refer to the Lambda Managed Instances documentation. The GitHub repository contains the complete benchmark code, SAM templates, and deployment instructions. Share your results in the comments and let the community know how Managed Instances performs on your workloads. To delete all benchmark resources and avoid ongoing charges, run the cleanup commands documented in the GitHub repository README.