ASRock Rack has developed an unlikely edge server based on NVIDIA’s industrial SoC, Thor. The Blackwell-era chip is being used to power the 2UXGI-THOR, a server aimed at the industrial and medical markets
On July 13, 2006, we launchedAmazon Simple Queue Service (Amazon SQS) as one of the first three services available to customers, alongside Amazon EC2 and Amazon S3. We had learned firsthand that distributed systems need a reliable way to pass messages between components without creating tight dependencies. If one service called another directly and that service was slow or unavailable, failures cascaded through the entire system. Message queuing solved this by letting services communicate asynchronously: a producer could drop a message into a queue and move on, while a consumer picked it up when ready. This approach kept individual service failures from affecting the rest of the system.
When Amazon SQS launched publicly in July 2006, it made this pattern available to every AWS customer. Twenty years later, that core function, decoupling producers from consumers, remains the reason customers use SQS. The scale, performance, and operational controls around it look very different now though.
Jeff Barr covered the first 15 years of SQS milestones in his 15th anniversary post, from the original 8 KB message limit in 2006 through FIFO queues, server-side encryption, and Lambda integration. Over the last five years, we have continued to scale SQS, added stronger security defaults, and introduced new capabilities that address increasingly complex workload patterns.
Key milestones between 2021 and 2026 High throughput mode for FIFO queues (2021): In May 2021, we launched general availability of high throughput mode for FIFO queues, supporting up to 3,000 transactions per second (TPS) per API action, a tenfold increase over the previous limit. We continued raising this ceiling over the following two years: to 6,000 TPS in October 2022, to 9,000 TPS in August 2023, and to 18,000 TPS in October 2023, before reaching 70,000 TPS per API action in select Regions by November 2023.
Server-side encryption with SSE-SQS (2021): In November 2021, we introduced server-side encryption with Amazon SQS-managed encryption keys (SSE-SQS), giving customers an encryption option that required no key management. In October 2022, we made SSE-SQS the default for all newly created queues, so customers no longer needed to explicitly enable it.
Dead-letter queue redrive enhancements (2021): We progressively expanded how customers recover unconsumed messages from dead-letter queues. In December 2021, we added DLQ redrive to source queue directly in the SQS console. In June 2023, we extended this capability to the AWS SDK and CLI through new APIs, including StartMessageMoveTask, CancelMessageMoveTask, and ListMessageMoveTasks. In November 2023, we added redrive support for FIFO queues.
Attribute-based access control, ABAC (2022): In November 2022, we introduced ABAC, giving customers the ability to configure access permissions based on queue tags rather than maintaining static policies as resources scaled.
JSON protocol support (2023): In November 2023, we added support for the JSON protocol in the AWS SDK, reducing end-to-end message processing latency by up to 23% for a 5 KB payload and lowering client-side CPU and memory usage.
Amazon EventBridge Pipes console integration (2023): We added the ability to connect a queue directly to EventBridge Pipes from the SQS console, routing messages to a broad range of AWS service targets without writing custom integration code.
Extended Client Library for Python (2024): We brought the Extended Client Library, previously available for Java, to Python developers, allowing messages up to 2 GB to be sent through SQS by storing the payload in Amazon S3 and passing a reference through the queue.
FIFO in-flight message limit increase (2024): We increased the in-flight message limit for FIFO queues from 20,000 to 120,000 messages, so consumers can process significantly more messages concurrently without being constrained by the previous ceiling.
Fair queues for multi-tenant workloads (2025): We introduced fair queues to mitigate the noisy neighbor problem in multi-tenant standard queues. By including a message group ID when sending messages, customers can prevent a single tenant from delaying message delivery for others, without any changes required on the consumer side.
1 MiB maximum message payload size (2025): We increased the maximum message payload from 256 KiB to 1 MiB for both standard and FIFO queues, helping customers send larger messages without offloading data to external storage. AWS Lambda event source mapping for SQS was updated in parallel to support the new payload size.
The constant underneath the change Despite two decades of feature additions, the fundamental use case for SQS has not shifted. Customers use it to decouple services, buffer bursts of traffic, and build systems that stay resilient when individual components fail. That same pattern now extends to AI workloads. Customers use SQS queues to buffer requests to large language models, manage inference throughput, and coordinate communication between autonomous AI agents operating as independent services. For an example of this architecture in practice, read Creating asynchronous AI agents with Amazon Bedrock.
Enterprise data architectures have become fundamentally distributed. Over the past decade, organizations have made deliberate investments across multiple platforms such as relational databases for transactional workloads, cloud data warehouses for analytics, object stores for unstructured data, and SaaS applications for domain-specific functions. Each was chosen to solve a specific problem, serve a specific team, or meet a specific performance requirement. The result is not accidental sprawl. It is a deeply heterogeneous data landscape shaped by intentional, workload-driven decisions. The challenge now is not consolidation, but interoperability: enabling these systems to function as a unified foundation for the next generation of AI-driven applications.
Agentic AI systems that autonomously reason, plan, and take action on behalf of users are moving rapidly from experimentation to enterprise production. These systems do not just retrieve information. They synthesize it, act on it, and learn from it. And unlike traditional analytics tools that can work with a well-scoped dataset, AI agents require something more demanding: unified, governed, and real-time access to all relevant enterprise data, regardless of where it lives.
This is the gap that matters most right now. Enterprises that have invested in building strong data capabilities across multiple providers are well-positioned, but only if those platforms can be accessed together, consistently, and with the governance controls that enterprise AI requires. Without a unified data foundation, AI agents operate with incomplete context, governance becomes inconsistent, and the promise of autonomous AI remains out of reach.
Solution approach
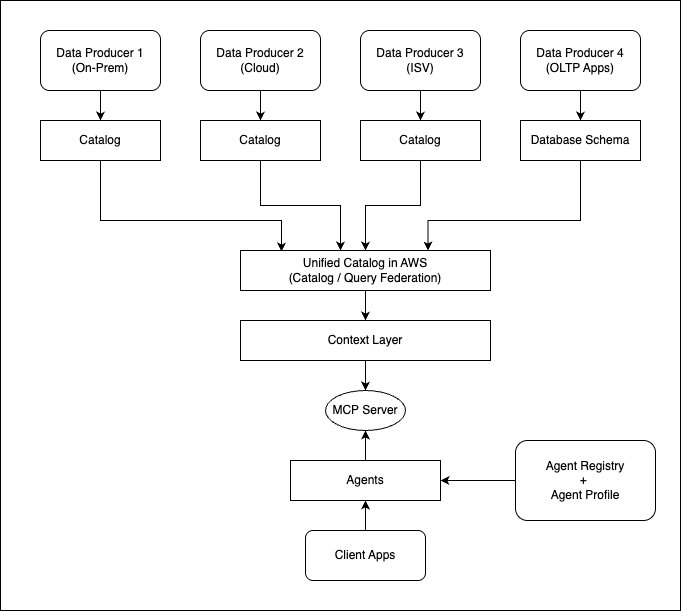
The following high-level architecture explains how you can onboard metadata catalogs and MCP servers to your context layer, which becomes the primary input for your AI agents.
Assuming your data products have a well-defined metadata catalog, you can take a unified-catalog-first approach, then build the context layer on top of it to let your AI agents discover all the context from one place. This helps bring in centralized governance and audit control, because every request gets routed through the centralized metadata catalog and context layer to simplify implementation of unified governance. In addition, this brings simplicity to enable business semantics, define attribute priorities, and define authoritative sources for the consumer use cases.
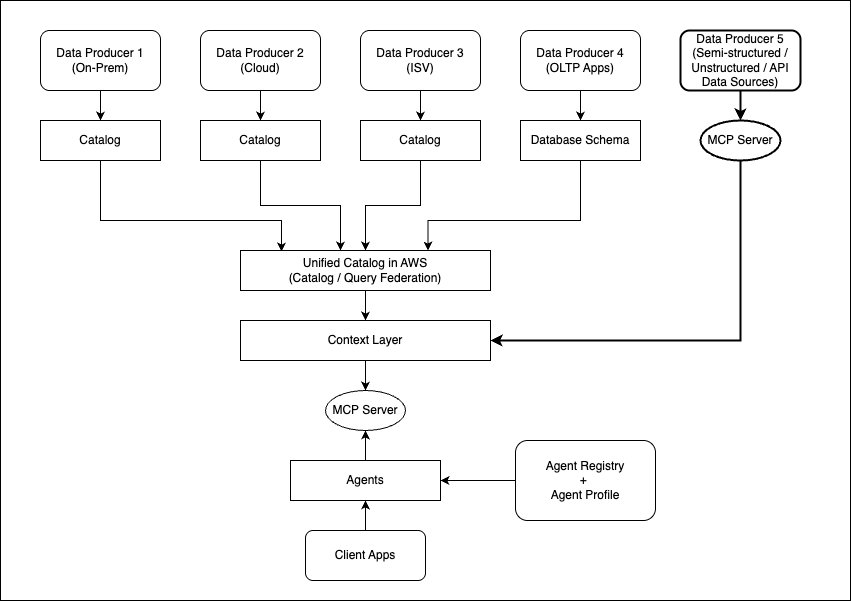
If any of the data sources does not have a well-defined metadata catalog, you can define Model Context Protocol (MCP) servers on them, and then directly onboard them to the context layer. For example, if you have semi-structured or unstructured datasets for which you do not have a well-defined metadata catalog, or you want to onboard third-party data sources through REST APIs, then you can add their respective MCP server to the context layer directly. The following architecture explains the extended flow for it.
In this series of posts, we demonstrate how you can unify the metadata catalog access across multiple providers, how you can enable AI agents to query the unified catalog, and how the context layer can be integrated to unify metadata from catalogs and MCP servers. We have divided the series into the following parts.
Part 1: Architecture approach with tradeoffs to unify a multi-cloud lakehouse architecture that can power Agentic AI (this post).
Part 2: Implementing an example solution to unify catalogs from multiple providers and deploy AI agents to query the unified data access layer.
Part 3: Integrate a context layer on top of the unified catalog for AI agents.
Part 4: Onboard additional data sources to the context layer through MCP servers and demonstrate the full solution.
This post focuses on explaining the architecture approach to build the open lakehouse architecture on AWS, unifying the metadata catalog across providers for the AI agents to access. In addition, it highlights the architecture trade-offs and best practices.
Use case
Every AI initiative launched on a fragmented data foundation is an initiative that will need to be rebuilt. Organizations that establish unified data access today are the ones that will scale Agentic AI with confidence tomorrow. Consider a large enterprise managing petabytes of data across a diverse set of environments:
On-premises: Network device telemetry, customer records, and operational databases.
Multiple cloud platforms: Marketing analytics, HR systems, and enterprise applications distributed across cloud providers.
Data platforms: Data science workloads, feature engineering pipelines, and finance and supply chain analytics running on specialized platforms.
SaaS applications: Salesforce, SAP, Zendesk, ITSM, and other business tools that each hold a critical piece of the enterprise data picture.
The business objective is to build a unified analytics and AI platform that can:
Query and analyze data across all environments without requiring full data migration.
Enforce consistent data governance and access control regardless of data location.
Power AI agents that can autonomously discover, query, and act on enterprise data.
Reduce total cost of ownership by eliminating redundant pipelines and storage.
This architecture directly addresses these needs by combining flexible data integration patterns, an open-table-format-based lakehouse architecture (with an example of Apache Iceberg), AI agent deployment to access unified metadata, and centralized governance.
Reference architecture
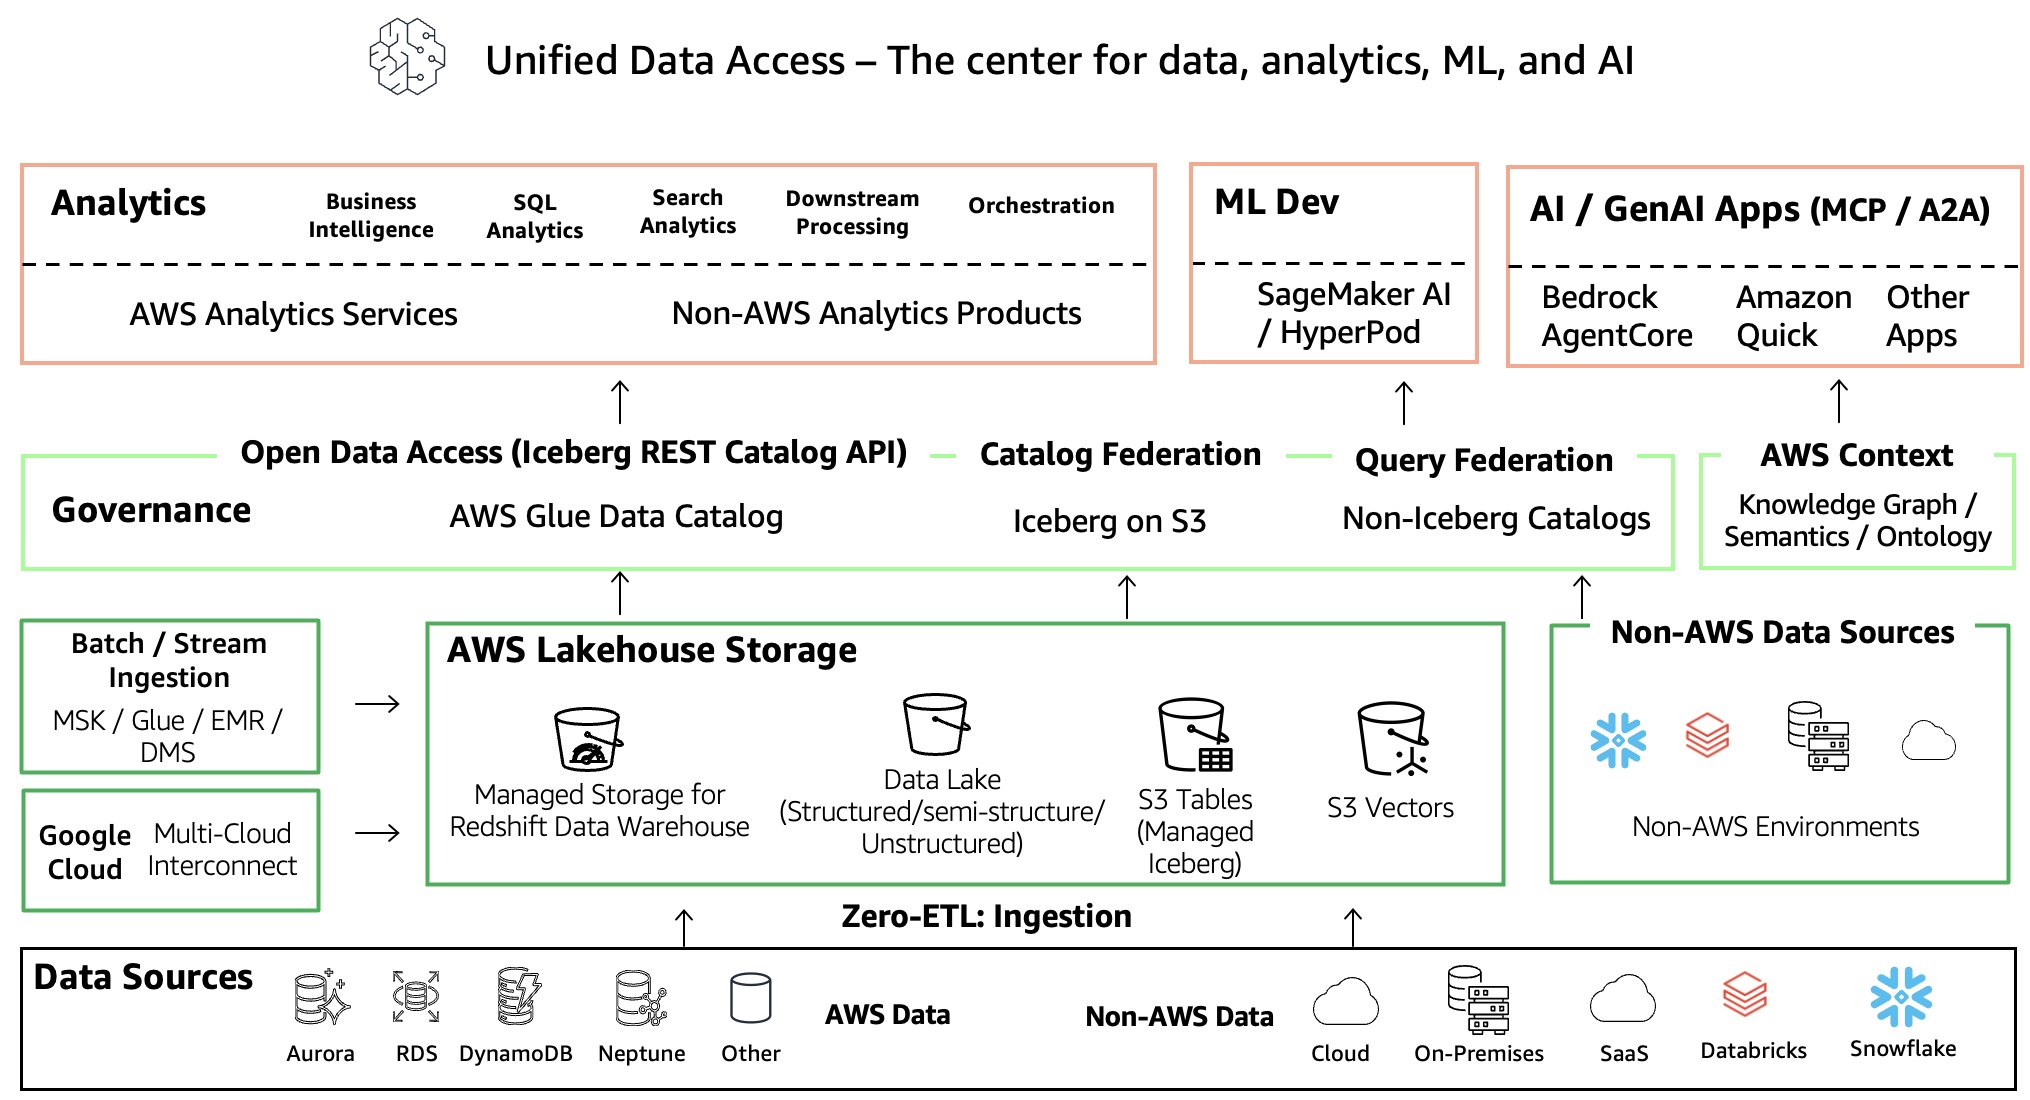
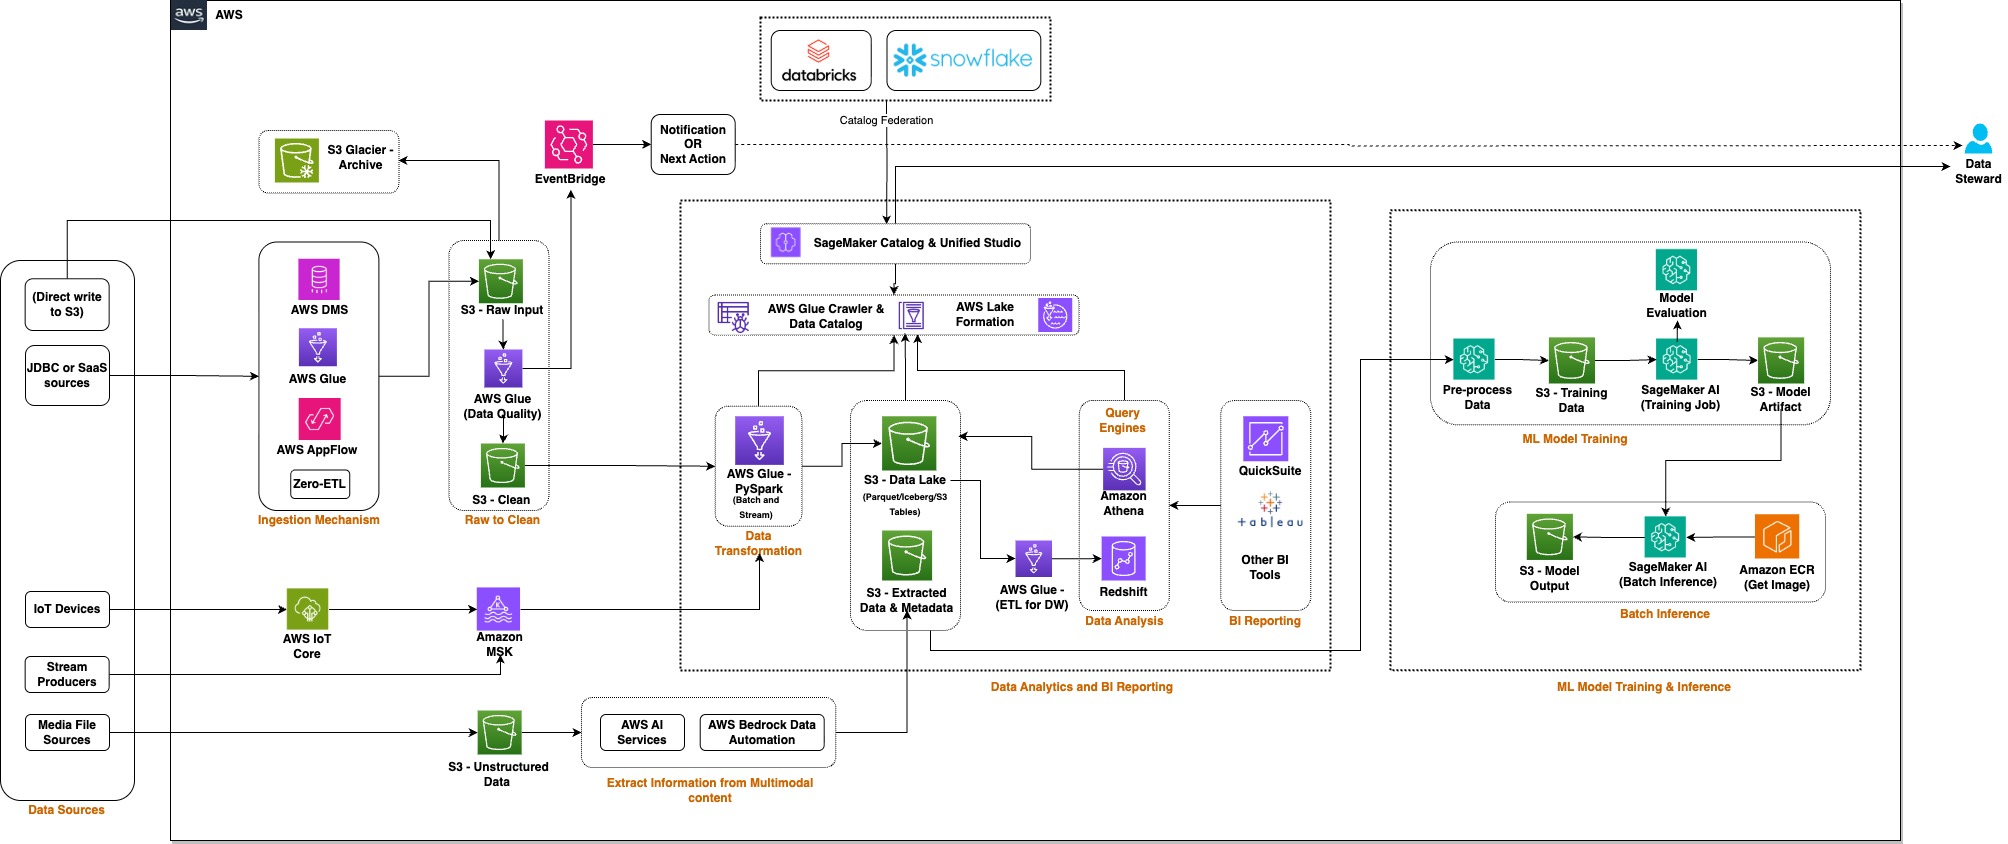
Before going deeper into a specific architecture, let’s revisit at a high level how the AWS open lakehouse architecture enables data ingestion and query or catalog federation to power analytics, machine learning development, and generative AI application development.
The following architecture diagram represents an end-to-end flow that includes:
Data ingestion to the data lake or data warehouse through Zero-ETL and batch or stream processing using AWS native services, or accessing data from Google Cloud Platform using AWS Interconnect – multicloud.
A centralized metadata catalog layer that includes data on AWS and metadata representation of non-AWS data sources using query or catalog federation.
A context layer that you can integrate to create a knowledge graph with ontology and business semantics that can enrich context for AI agents.
The consumption layer, which can include analytics, machine learning model development with Amazon SageMaker AI, and generative AI application development with Amazon Bedrock AgentCore, Amazon Quick, or other AWS and non-AWS AI applications.
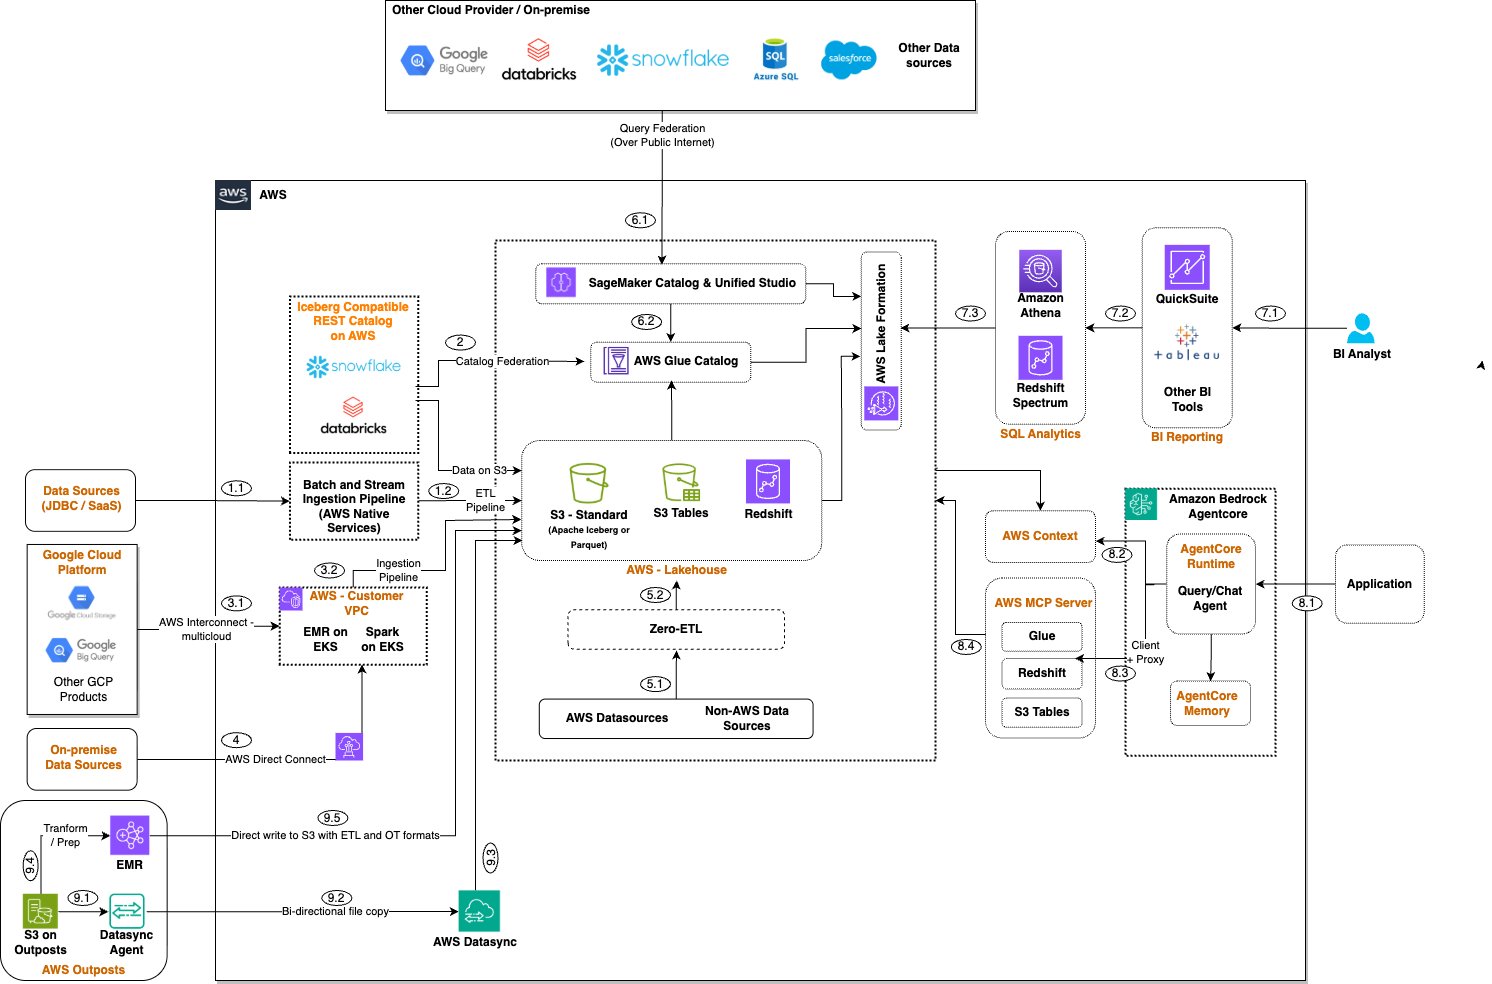
Let’s look at an expanded version of this architecture that details the data ingestion and data consumption patterns to build a unified data access layer on AWS that spans multiple cloud and ISV providers.
Expanded technical architecture walkthrough
The following architecture demonstrates the comprehensive AWS approach for metadata catalog consolidation through flexible integration patterns, and it also highlights patterns for building a lakehouse on AWS. Built on the open standards of Apache Iceberg for storage and governance through AWS Lake Formation, it creates a unified data foundation that connects existing investments without requiring wholesale migration, and it makes enterprise data AI-ready from day one. This architecture delivers value at every layer: business teams query across platforms without data movement, IT teams manage governance through a single federated layer with the flexibility to federate or ingest per use case, and compliance teams enforce policies once across all sources with full lineage and audit coverage.
The following are the key components of the architecture.
Data access methods
This section provides options to access data that is not available in AWS Glue Data Catalog and not available on AWS.
AWS Glue Data Catalog implements the Iceberg REST Catalog API specification, which enables seamless federation with Databricks, Snowflake, or other Iceberg-compatible catalogs set up with Amazon Simple Storage Service (Amazon S3) as the storage layer.
With the growing adoption of Apache Iceberg, catalog federation will become a common standard in the future and simplify metadata unification.
2. Query federation (Reference point 1.1)
Direct cross-cloud querying over the public internet to Google BigQuery, Azure SQL, Salesforce, and other platforms.
Real-time access to external data sources without replication, and seamless access with AWS analytics services.
Provides flexibility, because the catalog federation capability of the Iceberg REST catalog is limited to Iceberg tables only.
2.1. Secured private connectivity to Google Cloud Platform using AWS Interconnect for multi-cloud (Reference points 3.1, 3.2)
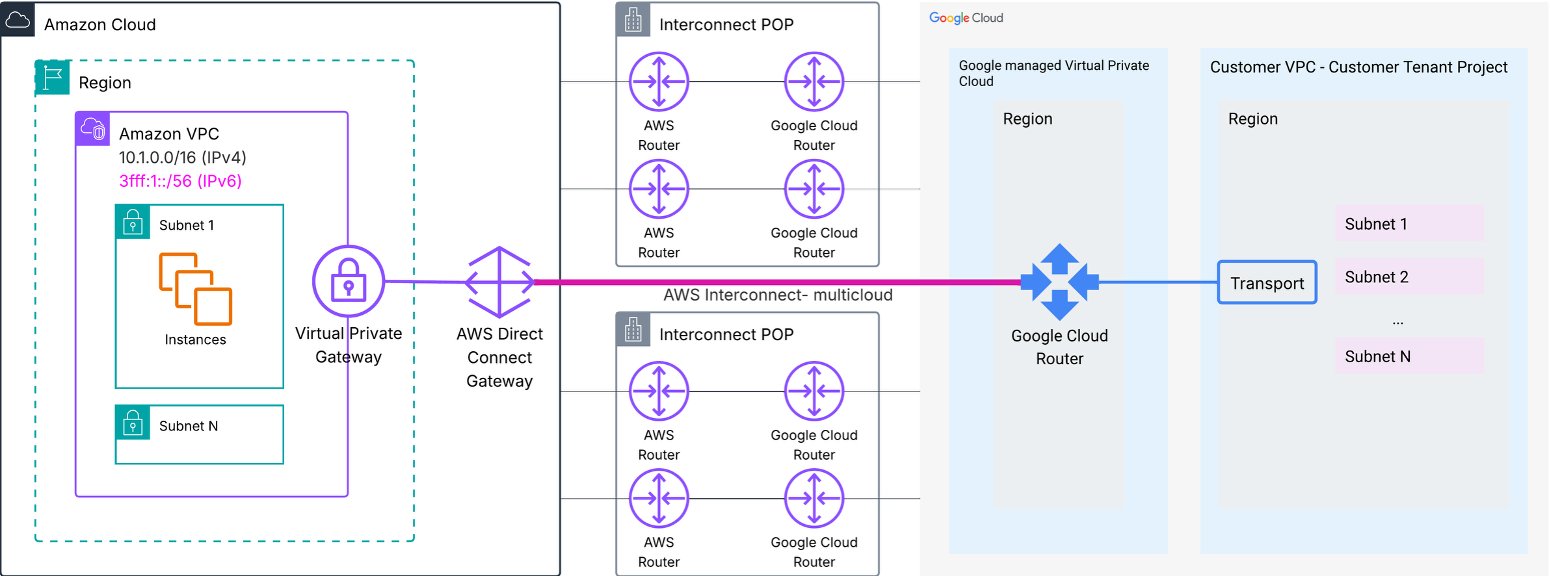
The default query federation approach makes the connection and transfers data over the public internet, which has its own latency implications depending on the target platform and the data volume transferred over the internet. During re:Invent 2025, AWS announced the public preview of AWS Interconnect – multicloud, which recently became generally available.
AWS Interconnect – multicloud is a managed service that provides private, high-speed, and secure network connections between Amazon Web Services (AWS) and other cloud providers, starting with Google Cloud Platform (GCP), with Microsoft Azure and Oracle Cloud Infrastructure (OCI) coming later in 2026. You can enable the integration with three steps: 1) specify the target cloud service provider, 2) select the destination Region on the other side, and 3) pick the required bandwidth.
The following architecture represents AWS and GCP integration with AWS Interconnect – multicloud.
On the AWS side, you need an AWS Direct Connect gateway (a global construct that acts as a route reflector), which you can attach to your Amazon Virtual Private Cloud (Amazon VPC) through a virtual private gateway or AWS Transit Gateway, or AWS Cloud WAN. On the GCP side, you need a Google Cloud Router that you attach to your customer VPC. Interconnect – multicloud offers pre-cabled capacity pools at shared Interconnect points of presence (PoPs) in selected Regions, where both AWS and GCP routers are co-located and pre-wired.
Because Interconnect – multicloud primarily routes traffic within the VPC through a private network, to benefit from it you need to keep your query engine or jobs within a customer VPC.
2.2. High network bandwidth with on-premises systems (Reference point 4)
AWS Direct Connect for high-bandwidth, low-latency on-premises connectivity.
Data ingestion methods
This section focuses on ways you can use to onboard datasets (complete or subset) to a lakehouse on AWS.
1. Zero-ETL: Data movement to AWS with Zero-ETL ingestion (Reference points 5.1, 5.2)
AWS Zero-ETL capabilities for seamless data loading from AWS and non-AWS sources.
2. Extract, transform, load (ETL): Extract data from JDBC or SaaS sources and transform through a batch or stream pipeline (Reference points 3.1, 3.2)
Option to design batch and stream ingestion pipelines using AWS managed services with open source data processing engines such as Apache Spark and Apache Flink.
Hundreds of connectors available as part of AWS Glue to extract data from JDBC and SaaS sources, and the flexibility to design custom connectors that can run on serverless Glue clusters.
The following architecture expands the flow 1.1 to 1.2 ingestion method that integrates AWS services to onboard data to the Amazon S3 raw layer and then takes it through an ETL pipeline for data cleansing and transformations. It also includes steps to onboard unstructured data to Amazon S3 using Amazon Bedrock Data Automation, and taking the lakehouse data for machine learning development with Amazon SageMaker AI.
You can also use AWS Interconnect – multicloud to run Spark jobs (Spark with Amazon EMR on EKS or open source Spark on any compute within a customer VPC) to ingest and transform data from Google Cloud with private connectivity.
3. Accessing data from Google Cloud over a private network
Refer to the preceding data access methods (3.1 and 3.2).
4. Onboarding data from AWS Outposts (S3 on Outposts) (Reference points 9.1 to 9.5)
Option to onboard S3 on AWS Outposts data to regional Amazon S3 through AWS DataSync (reference 9.1 to 9.3), which might be a better fit to sync files as-is through a scheduled batch or an event-driven approach.
Flexibility to transform the S3 on Outposts data using an Amazon EMR clusters on Outposts job, and then directly write the transformed output to a regional Amazon S3 bucket in the formats you want (including open table formats such as Apache Hudi, Apache Iceberg, and Delta Lake).
Lakehouse foundation with Apache Iceberg
By standardizing on Apache Iceberg, you’re not choosing AWS over your other platforms. You’re choosing interoperability and future flexibility. Your data becomes truly portable across any Iceberg-compatible engine.
Open table format: Industry-standard format supported across AWS, Databricks, Snowflake, and other platforms, which eliminates vendor lock-in.
ACID transactions: Reliability with full transactional consistency.
Time travel and schema evolution: Built-in versioning and flexible schema management.
Performance optimization: Advanced features such as hidden partitioning, partition evolution, and metadata management.
Note that lakehouse storage is not limited to the Apache Iceberg format, and you have the flexibility to include other open table formats (for example, Apache Hudi and Delta Lake) or file formats (for example, Apache Parquet and Apache Avro).
Unified governance and access control
AWS governance capabilities transform the lakehouse from a storage layer into a fully governed data platform. This delivers security, compliance, and data quality out of the box, applied consistently across all data sources including federated catalogs. A unified catalog consolidates metadata from AWS and non-AWS sources with generative AI-powered business glossary generation, while automated ML-powered classification identifies sensitive data (for example, PII, PHI, and financial data) across structured and unstructured datasets. AWS Identity and Access Management (AWS IAM) and AWS Lake Formation enforce fine-grained access control at the row, column, cell, and tag level, applied consistently across Amazon Athena, Amazon Redshift Spectrum, Amazon EMR, and federated sources. End-to-end data lineage tracking provides visual data flow graphs, impact analysis, and compliance audit trails. When AI agents explore metadata from the unified catalog and submit a query to Amazon Athena for execution, the Lake Formation fine-grained access control filters data based on the user interacting with the AI agent.
For the foundation model integrated into your AI agents, you can use Amazon Bedrock Guardrails, which implements customized safeguards to block harmful content and minimize hallucinations. Amazon Bedrock AgentCore provides fine-grained policy control over agent actions with real-time enforcement and managed authentication for agents accessing AWS and third-party services.
A comprehensive audit and compliance stack spans Amazon CloudWatch, AWS CloudTrail, AWS IAM, AWS Key Management Service (AWS KMS), AWS Audit Manager, and AWS PrivateLink. This stack makes sure every agent invocation is traceable, every key is managed, and every configuration is automatically mapped to frameworks including ISO, SOC, GDPR, and HIPAA.
When an end user interacts with the AI chat assistant, the layers of security and governance should go through the following.
Layer 1: Who can access?
Enable Active Directory and single sign-on integration for user authentication, and a combination of AWS IAM roles for AWS API-level authorization.
Layer 2: What can they see?
Integrate an agent profile to define what datasets each agent can access, because not all agents should have access to all datasets.
Enable fine-grained access control on the metadata layer using AWS Lake Formation that can filter rows and columns.
Enable data masking as applicable while the query responses are served through the query engine.
Layer 3: What can the agent do?
Control agent actions by restricting them to read-only, and apply restrictions to INSERT, UPDATE, and DELETE if the agents are supposed to query only.
Apply a limit on the number of rows that can be returned from the query, and apply a query scan limit to reduce cost.
Layer 4: What does the agent reveal?
Enable output filtering to make sure no PII is included.
Apply Amazon Bedrock Guardrails on large language model (LLM) responses to make sure the model does not produce anything inappropriate.
In addition, enable audit logging of all queries to make sure future audit and compliance needs can be met.
AWS offers a complete analytics ecosystem that includes the following.
Amazon Athena: Serverless SQL queries with Iceberg v2 support, including provisioned capacity for consistent performance and workgroups for resource and cost management.
Amazon Redshift Spectrum: Federated queries across the data warehouse and Iceberg data lake.
Amazon Quick Sight: Enterprise visualization with governed access to all data.
AWS Glue and Amazon EMR: Distributed data processing capability for enterprise transformations.
AI-ready architecture (Reference points 8.1 to 8.4)
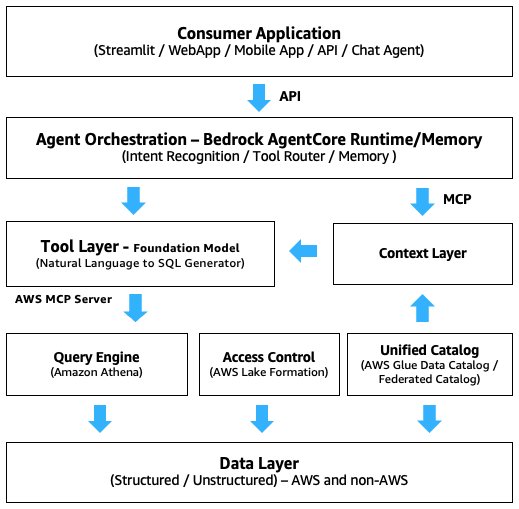
A consolidated lakehouse architecture helps you make data ready for AI agents that can access the data through readily available MCP servers or through the AWS SDK for Python (Boto3) for Amazon Athena or Amazon Redshift Spectrum. AI agents can integrate the AWS MCP Server to interact with AWS analytics services such as AWS Glue, Amazon Athena, and Amazon S3 Tables, a capability of Amazon S3, to query both data and metadata.
AI agents need context to understand how the catalog tables and their attributes are linked to each other, how users have queried them in the past, or what priorities are defined to understand which one is an authoritative source for a particular natural language question. To enable the AI agent with additional context, we can integrate the AWS Context service that was pre-announced recently at the AWS New York Summit 2026.
Governance integration: AI agents automatically inherit Lake Formation permissions, because the agent can submit the SQL query to be run through Amazon Athena or Amazon Redshift Spectrum. This makes sure they only access data that users are authorized to see. Amazon SageMaker Unified Studio data lineage tracks AI agent queries for full auditability.
The following diagram represents how the AI agent request flow looks.
This architecture delivers value across every layer of the organization. Business teams gain faster time-to-insight by querying data across all platforms without waiting for data movement, while eliminating duplicate storage and reducing transfer costs through federation. The Apache Iceberg open table format ensures data portability and freedom from vendor lock-in. For IT and data teams, a single governance layer across all sources, including federated catalogs, reduces operational complexity, while the flexibility to choose between federation and ingestion for each use case, combined with the elastic AWS infrastructure and the petabyte-scale metadata architecture of Iceberg, delivers both agility and scalability. Data governance and compliance teams benefit from a single point of policy enforcement across all data regardless of location, complete lineage and access logs for audit and compliance reporting, automated sensitive data classification, and policies that are defined once and enforced everywhere, including across federated sources.
Architecture tradeoffs and best practices
The following are a few key trade-offs you need to consider while designing the solution.
Data ingestion and access methods
Use catalog federation (Iceberg REST) when:
The source platform supports the Iceberg REST API (Databricks, Snowflake Polaris).
Data is already in Iceberg format with Amazon S3 backed storage.
You want bidirectional discovery (AWS tables visible in Databricks or Snowflake too).
Use query federation (Amazon SageMaker Lakehouse architecture or AWS Glue connectors) when:
The source is BigQuery, SQL Server, or another non-Iceberg platform.
Data must stay in the source cloud (sovereignty, contractual, or latency reasons).
Real-time access is required without replication lag.
Use ingestion (Zero-ETL, AWS Glue, or Amazon EMR) when:
Data is accessed frequently with a low-latency requirement by AI agents or high-concurrency analytics.
The business decides to build a data lake and warehouse on AWS.
You need full governance, time travel, and performance optimization.
Use AWS Interconnect – multicloud when:
You need real-time or near-real-time query federation to GCP data sources (BigQuery, AlloyDB, Cloud Spanner) and latency or security requirements prohibit public internet routing.
You have high-volume, recurring data transfers between AWS and GCP where public internet egress costs or bandwidth variability are unacceptable.
Your organization has compliance or regulatory requirements mandating that data never traverse the public internet (HIPAA, PCI-DSS, or financial services regulations).
You need bidirectional connectivity, such as GCP workloads calling AWS APIs, or AWS workloads calling GCP APIs, both over private paths.
Choosing between federation and ingestion based on use case
Dimension
Federation (Query in Place)
Ingestion (Move to AWS)
Data freshness
Real-time or near-real-time
Dependent on ingestion frequency
Query performance
Subject to source system latency and network
Subject to data volume and operation, avoids cross-cloud network latency
Cost
Lower storage cost. Higher per-query cost for cross-cloud egress
Integrating Amazon Bedrock AgentCore Gateway and Amazon Bedrock AgentCore Runtime based on use case
The following are key differences between AgentCore Gateway and AgentCore Runtime that are relevant for our use case.
Dimension
Amazon Bedrock AgentCore Gateway
Amazon Bedrock AgentCore Runtime
Timeout
5 minutes (hard limit)
15 min sync / 8 hours async
Statefulness
Stateless (per-request)
Stateful (session-based)
Best for
Lightweight API proxying
Long-running data processing
Your lakehouse queries
Will time out frequently
Handles multi-hour jobs
Because AgentCore Gateway has a 5-minute hard timeout limit, use AgentCore Runtime for data processing jobs.
AWS Glue ETL jobs can run for minutes to hours.
Amazon Redshift queries on large datasets routinely exceed 5 minutes.
Athena federated queries (especially cross-cloud through Interconnect) can be slow.
Iceberg table scans on multi-TB datasets take time.
You can use AgentCore Gateway if the scope is limited to Glue Data Catalog interactions to fetch metadata schema, because that won’t run for more than 5 minutes.
Design considerations for production implementation
In practice, there are multiple aspects to consider when deploying the solution for production. The following summarizes a few of the key issues you might encounter and approaches to address them.
Catalog federation: The metadata drift problem
One of the first surprises in production is metadata drift, the state where your federated catalog no longer reflects the actual schema of the source system, because the source system’s metadata changes are not reflected in the unified catalog. The agent continues to generate SQL against the stale schema, producing silent failures that are hard to trace.
The following are a few ways you can address the metadata drift issue.
Implement a catalog refresh schedule. Even a daily Glue crawler run against federated sources catches most drift before it causes agent failures.
Add schema validation as a pre-query step in your agent tool. Before running SQL, verify that the referenced columns exist in the current catalog metadata.
Instead of pulling metadata changes from the source in a scheduled manner, you can design an event-driven system, where the source system triggers a push event to run the schema change in the federated catalog.
Query federation: Latency is non-deterministic
Query federation works well for moderate data volumes, but latency becomes non-deterministic at scale. A query that returns in 3 seconds during testing can take more than 10 seconds in production when the source system is under load, the network path is congested, or the federated connector is cold-starting.
The following are a few approaches you can consider to improve the performance.
Set explicit query timeouts in your Athena execution context. Without them, a slow federated query will block your agent indefinitely.
Implement query result caching for frequently asked questions. Most business users ask the same questions repeatedly, and caching at the agent layer improves perceived performance.
For time-sensitive use cases, consider caching aggregated data in an AWS lakehouse on a schedule rather than querying live. This trades freshness for reliability.
AgentCore memory: Statefulness cost
AgentCore Memory enables stateful conversations, but in production, unbounded memory accumulation creates its own problems. An agent that remembers every conversation eventually starts surfacing stale context. For example, a user who asked about Q3 revenue six months ago gets that context injected into a Q1 query today.
The following are a few ways you can optimize cost and improve relevance.
Set explicit memory expiry (we use 30 days as shown in the implementation) and enforce it consistently.
Use session-scoped memory for transactional queries and long-term memory only for user preferences and recurring patterns.
Implement a memory review step in your LangGraph workflow. Before invoking the model, filter retrieved memories by recency and relevance score rather than injecting all of them.
LangGraph orchestration: When tool calls loop
The conditional routing of LangGraph is powerful, but in production we observed a failure mode where the agent enters a tool call loop. The model repeatedly calls the same tool with slightly different parameters, never reaching a satisfactory answer. This typically happens when the tool returns partial or ambiguous results and the model keeps trying to refine.
What we learned:
Add a maximum tool call counter in your LangGraph state. If the agent has called tools more than N times in a single session, force a graceful exit with a summary of what was found.
Return structured, unambiguous responses from your tools. Include row counts, column names, and explicit null indicators so the model can reason clearly about completeness.
Log every tool invocation with its input and output. This is the single most valuable debugging artifact when diagnosing agent misbehavior in production.
Handling hallucination risks in federated agent architectures
This is the most important section for teams moving from prototype to production. Hallucination in agentic AI systems that query real data is qualitatively different from hallucination in general-purpose LLMs, and it is more dangerous because the outputs look authoritative.
There are three distinct hallucination risk zones in a lakehouse AI agent:
SQL generation: The model generates SQL that is syntactically valid but semantically wrong. For example, when asked “What is our revenue growth this quarter?”, the model might generate a query that compares the wrong date ranges, uses the wrong aggregation function, or joins tables on incorrect keys, and then returns a confident, formatted answer with the wrong numbers.
Cross-source synthesis: When the agent queries multiple federated sources and synthesizes results, the risk compounds. The model may correctly retrieve customer counts from Amazon S3 and revenue figures from Snowflake, but incorrectly draw conclusions that aren’t supported by either dataset individually.
Memory-augmented reasoning: When long-term memory is active, the model may blend historical context with current query results in ways that are factually incorrect. For example, it might apply a business rule that was true six months ago but has since changed.
To improve, before any agent output informs a business decision, apply the following three-step validation framework:
Step 1: Source verification. Can you trace the answer back to a specific table, column, and row count? If the agent can’t show you the SQL and the row count, the answer is unverified.
Step 2: Reasonableness check. Does the answer fall within expected ranges? A sudden 10x spike in customer count is a signal to investigate.
Step 3: Cross-validation. For critical decisions, run the equivalent query directly in Athena or your BI tool and compare. Discrepancies reveal either a model reasoning error or a data quality issue. Resolve both before the answer is trusted.
These lessons don’t diminish the value of the architecture. They make it production-ready. The teams that move fastest with agentic AI are not the ones who skip these guardrails. They’re the ones who build them in from the start and spend less time firefighting in production.
Alternative to the unified catalog approach
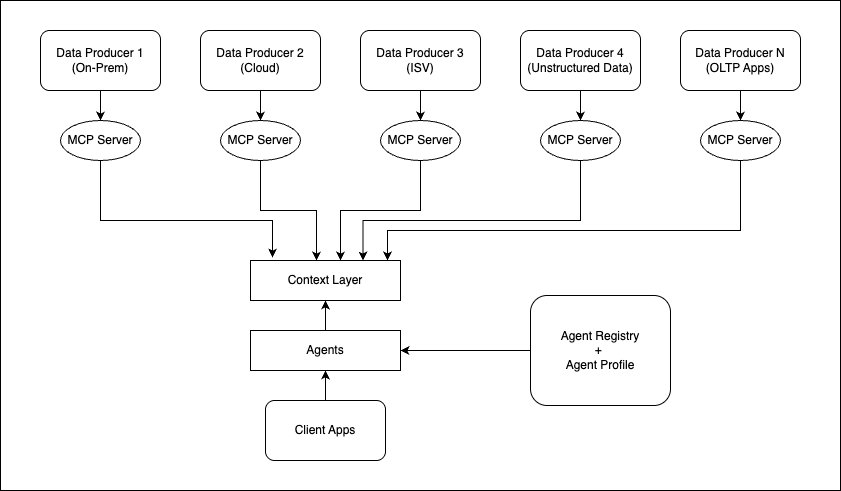
In case you face technical and process challenges to unify catalogs across providers, you can let each data producer expose the metadata and data through MCP servers, as represented in the following diagram. In this approach, each producer takes the responsibility of maintaining the MCP servers and exposing them to the context layer. While this approach provides autonomy to data owners to operate independently and with flexibility, it also creates operational overhead to synchronize all metadata in a consistent way.
What’s next
In Part 2 of this series, we walk through the full implementation step by step, including hands-on scripts to:
Load example sales datasets into Databricks and marketing data to Snowflake as Iceberg tables, and federate them into AWS Glue Data Catalog through the Iceberg REST API.
Register Google BigQuery as a native federated data source in Amazon SageMaker, instead of a traditional AWS Lambda connector integration.
Create a customer master table as a native Iceberg table in Amazon S3.
Run a single SQL query in Amazon Athena that joins all four sources across two federation patterns, with no data movement.
Deploy an AI agent on Amazon Bedrock AgentCore that can autonomously query the same unified catalog using Amazon Athena and answer complex business questions in natural language queries. In addition, integrate AgentCore Memory to persist user context.
Conclusion
In this post, we summarized how you can unify data access across multiple cloud and ISV providers on AWS with the combination of catalog federation, query federation, and data movement to AWS. We then explained how AWS Glue Data Catalog and Lake Formation help provide unified catalog and access governance, and how AI agents hosted in Amazon Bedrock AgentCore can access it using MCP servers to explore the metadata context, convert user natural language queries to SQL, and use Amazon Athena to run the query across data sources to get the response to the end user. In addition, we provided an overview of different data ingestion methods to build a lakehouse architecture on AWS, including AWS Interconnect – multicloud and where it adds value.
We also provided architecture trade-offs and best practices to integrate the service capabilities. In the next post (Part 2), we will take a specific use case and provide a step-by-step implementation guide to unify the catalog and deploy the agent to Amazon Bedrock AgentCore.
When you process over 500 million transactions per month, every second of undetected anomaly means failed payments, lost revenue, and eroded merchant trust. Static monitoring thresholds that worked for thousands of merchants collapse at the scale of millions, and the cost of missed detection compounds exponentially.
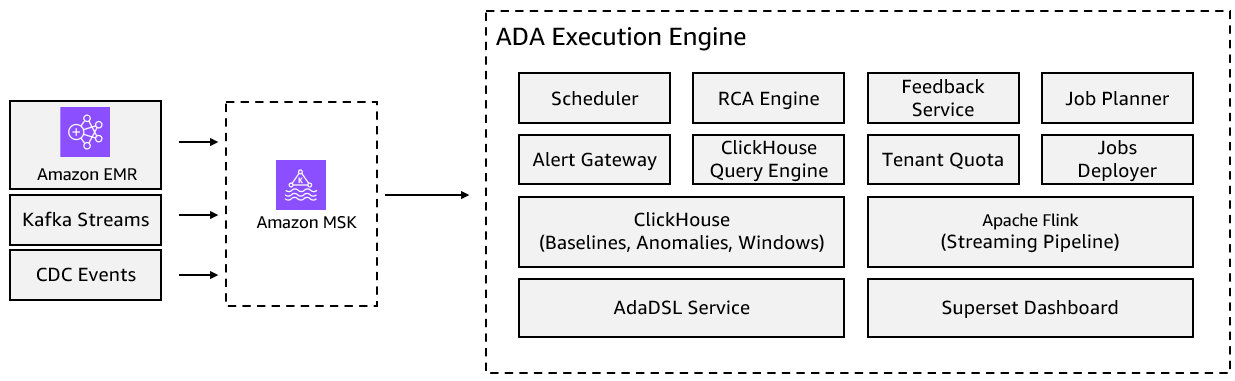
In this post, we explore Razorpay’s anomaly detection and alerting platform (ADA) architecture using Amazon Managed Streaming for Apache Kafka (Amazon MSK) and other AWS services. According to Razorpay the system detects transaction anomalies in under 30 seconds, supports thousands of merchant-level alerts, and reduced monitoring costs by approximately 80 percent. The platform maintains 99.99 percent uptime for over 500 million transactions per month.
Founded in 2014, Razorpay has become one of India’s largest full-stack financial solutions companies, powering payments, banking, and business growth for over 10 million businesses. With offerings spanning payment gateway, RazorpayX for business banking, and Razorpay Capital for lending, the company processes over 500 million transactions per month across payments, payroll, banking, and cross-border services.
At this scale, Razorpay’s data platform processes more than 5 billion events daily. Every transaction, settlement, and disbursement generates events that must be monitored in real time for anomalies. These range from systemic degradations and latency regressions to card-testing fraud attacks and velocity abuse at the merchant level.
For a regulated payments platform, undetected anomalies carry consequences far beyond technical metrics. A missed fraud pattern can mean direct financial losses running into millions of rupees. It can also bring regulatory scrutiny from the Reserve Bank of India and irreversible damage to merchant confidence, the foundation of Razorpay’s business. Razorpay needed real-time anomaly detection, but the existing infrastructure couldn’t keep pace with the company’s growth.
The problem: When static thresholds can’t keep up with scale
As Razorpay scaled from thousands to millions of merchants, the existing monitoring infrastructure hit critical limitations across four dimensions.
Anomaly blind spots
Systemic degradations, latency regressions, and success-rate drops went undetected until customers complained. By the time a human operator noticed a 15 percent drop in payment success rates for a specific gateway-merchant combination, thousands of transactions had already failed.
Fraud at velocity
Card-testing activity, velocity abuse, and geo-anomalies at the merchant level required sub-minute detection. Unauthorized users could generate hundreds of micro-transactions in seconds. Traditional batch detection was too slow to prevent damage.
Static thresholds don’t scale
The existing tooling relied on static thresholds with no adaptive baselines. This created a painful dilemma: set thresholds too tight and drown in false alarms (alert fatigue), or set them too loose and miss real incidents.
High cardinality equals high cost
Monitoring thousands of merchants individually on the previous architecture cost approximately $500K per year: $250K in licensing fees plus $250K in infrastructure, with fundamental scalability limits. ThirdEye queried a 21-day lookback at query time, enforcing a 1–2 minute service level agreement (SLA) minimum. The system was not designed for thousands of concurrent merchant-level alerts, a limitation confirmed by the vendor.
Solution overview: ADA: Anomaly detection and alerting
Razorpay built ADA (Anomaly Detection and Alerting), a configurable, multi-tenant engine for real-time anomaly detection and fraud prevention. The platform’s design centers on three core principles that address the limitations of the previous architecture.
First, ADA is declarative: users express what to detect, not how. A single domain-specific language (AdaDSL) drives both batch and streaming execution, eliminating the need for engineers to write custom detection code for each new alert. Second, ADA is adaptive. Dynamic baselines incorporate calendar-aware patterns (day-of-week, time-of-day, holiday adjustments) and machine learning (ML)-compatible thresholds that replace brittle static rules. Third, ADA is inherently multi-tenant: Payments, Payroll, and Banking each operate with isolated detection logic while sharing underlying infrastructure. This design removes the need to maintain separate monitoring stacks per business unit.
Amazon MSK serves as the event backbone of ADA, ingesting transaction events, distributing detection rules, and connecting the components of the real-time pipeline.
Architecture: Amazon MSK as the streaming backbone
The ADA architecture positions Amazon MSK as the core integration layer connecting event producers to detection engines and alert consumers. Payment authorization, settlement, and disbursement events flow through Kafka topics managed by Amazon MSK. With Razorpay processing over 500 million transactions per month and 5 billion events daily, the ingestion layer must absorb high throughput with zero data loss.
High-throughput event ingestion
The architecture uses tenant-partitioned topics. Each business unit (Payments, Payroll, Banking) publishes to logically isolated topics while sharing physical infrastructure. This design supports independent consumer groups per tenant with predictable throughput guarantees.
Change Data Capture (CDC) events from Razorpay’s core transactional databases (Amazon Aurora MySQL-Compatible Edition) flow through Debezium and a Kafka Streams-based Harvester service into Amazon MSK. Application events from payment services also publish directly to Amazon MSK topics via native Kafka producers.
Why Amazon MSK as the backbone
Amazon MSK serves as the architectural backbone of ADA, fulfilling four critical functions that together support reliable, real-time anomaly detection at scale. At the ingestion layer, Amazon MSK absorbs the full stream of transaction events with three-replica durability. If downstream consumers experience an outage, they resume from their last committed offset without data loss. Beyond ingestion, Amazon MSK is the event distribution backbone of detection rules. AdaDSL definitions authored by domain experts are serialized and published to a dedicated Kafka snapshot topic, which Flink jobs consume as a broadcast stream.
This delivers hot-reloadable rule updates without pipeline restarts, a critical capability when detection logic must evolve daily. Amazon MSK further supports tenant isolation at the topic level. Payments, Payroll, and Banking events flow through isolated topic partitions that support independent scaling and consumer group management per business unit. Finally, Amazon MSK fully decouples event producers from detection consumers, meaning new detection logic can be deployed, scaled, or rolled back without touching production payment flows.
Real-time stream processing with Apache Flink
Apache Flink acts as the stateful stream processing engine between Amazon MSK and the detection/alerting layer. The Flink pipeline implements five key stages:
Kafka Source (tenant-partitioned topics) – Consumes events from Amazon MSK with exactly-once semantics using Flink’s Kafka connector.
Event-Time Assignment + Watermarking – Assigns event timestamps and generates watermarks with a late-arrival tolerance of 2× the window size.
KeyBy (tenant_id, entity_key) + Windowed Aggregation – Partitions the stream by tenant and merchant, then computes windowed aggregates (success rates, latencies, transaction volumes).
Async I/O – Baseline Fetch from ClickHouse. Non-blocking lookups against pre-computed baselines stored in ClickHouse, supporting 1,024 concurrent requests.
Rule Evaluation (threshold / ML / CEP) – Evaluates AdaDSL rules against the enriched stream. This includes Complex Event Processing (CEP) patterns for sequence detection (for example, five consecutive declines followed by a success, a signature of card-testing fraud).
The pipeline outputs to three sinks:
anomalies_fct to ClickHouse for anomaly persistence and historical analysis.
Alert Gateway to Slack/PagerDuty for immediate notification.
windows_fct for reconciliation against batch baselines.
AdaDSL: Declarative detection at scale
AdaDSL abstracts detection logic into human-readable declarations that platform engineers and domain experts can author without understanding the underlying execution mechanics. A single definition compiles to both a ClickHouse Materialized View selector and a Flink CEP pattern, supporting consistent detection semantics across batch and streaming modes.
AdaDSL updates are distributed via the Amazon MSK snapshot topic. When an engineer modifies a rule, it’s serialized to Kafka and consumed by Flink as a broadcast state update. The change propagates to all running pipeline instances without redeployment. This is an important architectural advantage: the detection logic evolves independently of the infrastructure.
Reliability and fault tolerance
The architecture delivers 99.99 percent availability through multiple layers of resilience:
Amazon MSK is deployed across three Availability Zones with replication.factor=3 and min.insync.replicas=2, paired with producer-side acks=all. No single broker failure causes data loss or ingestion interruption, because the durability guarantee depends on all three settings working together. Combined with configurable retention policies, Amazon MSK provides a meaningful replay window for consumer recovery.
Flink checkpointing to Amazon Simple Storage Service (Amazon S3) provides exactly-once processing semantics. If a Flink task fails, the job manager restores from the latest checkpoint and resumes processing from the corresponding Kafka offsets. No events are lost or duplicated.
Idempotent sinks: Dedupe keys (tenant:AdaDSL:version:entity:window_start) prevent reprocessed events from creating duplicate anomaly records or alerts.
Event-time watermarks: 2× window tolerance handles late-arriving events gracefully, supporting detection accuracy even under network delays.
Results and business impact
The migration from Pinot + ThirdEye to ADA on Amazon MSK and Apache Flink delivered measurable improvements. The platform achieved approximately 80 percent cost reduction compared to the previous architecture while maintaining a 99.99 percent uptime SLA. Anomaly detection latency in streaming mode is under 30 seconds, and the system processes over 5 billion events daily. It supports thousands of concurrent merchant-level alerts with full multi-tenant isolation across Payments, Payroll, and Banking.
Operational improvements
The ADA platform delivered significant operational improvements across detection accuracy, speed, and team autonomy:
Alert fatigue removed – Adaptive baselines with calendar-aware patterns (day-of-week, time-of-day, holiday adjustments) reduced false positives by over 90 percent compared to static thresholds.
Mean time to detection reduced from minutes to seconds – Sub-30-second streaming detection replaced batch detection cycles that previously required 1–2 minutes minimum.
Self-service detection – Domain experts in Payments, Payroll, and Banking teams author their own AdaDSL rules without requiring platform engineering involvement.
Unified platform – One system for anomaly detection, fraud detection, alert routing, and reconciliation across all business units.
Key learnings and best practices
Throughout the design and implementation of ADA, Razorpay identified several architectural principles that proved essential at scale:
1. Separate rule definition from execution
A declarative DSL lets domain experts define detection logic while the platform decides batch or streaming execution. This separation allowed Razorpay to scale the number of active detection rules from dozens to thousands without proportional engineering effort.
2. Use Amazon MSK as the unifying backbone
Kafka’s publish-subscribe model naturally decouples event producers from detection consumers. Beyond basic event transport, Amazon MSK serves as the distribution mechanism for rule updates (broadcast state), tenant isolation (topic partitioning), and fault tolerance (offset-based replay). Investing in the streaming backbone early benefited every subsequent design choice.
3. Combine Flink streaming with ClickHouse baselines
Flink excels at sub-minute, stateful detection. ClickHouse excels at deterministic baseline computation and historical context. Rather than forcing one engine to do both, the hybrid architecture plays to each engine’s strengths.
4. Design for multi-tenancy from day one
Shared infrastructure with tenant isolation (row-level security in ClickHouse, scoped topics in Amazon MSK, tenant-partitioned Flink pipelines) keeps operational costs low while serving multiple business units with independent SLAs.
5. Build for extensibility
A plugin-compatible architecture allows ML models (ETS/Prophet for forecasting), CEP patterns (Flink CEP for sequence detection), and custom root cause analysis (RCA) strategies to be added without platform-level changes. Razorpay’s roadmap includes large language model (LLM)-assisted RCA and autonomous AdaDSL generation.
Conclusion
Razorpay transformed its anomaly detection from static-threshold monitoring on Pinot + ThirdEye to an adaptive, real-time system on Amazon MSK and Apache Flink.
This reflects a pattern increasingly common among high-scale FinTech platforms: a reliable, high-throughput streaming layer is not an optimization. It’s a prerequisite for operating payment infrastructure at scale.
Amazon MSK forms the backbone that allows Razorpay to ingest 5 billion events daily and distribute detection rules in real time. It also isolates multiple business units on shared infrastructure and provides exactly-once processing guarantees for financial transaction monitoring. Apache Flink transforms those raw event streams into sub-30-second anomaly detection with CEP-based fraud pattern matching.
For platform engineers building real-time monitoring for financial services, the takeaway is clear. Invest in the streaming backbone early, design for declarative extensibility, and let managed services absorb the operational complexity of distributed stream processing.
If you’re building real-time monitoring for a high-throughput transactional system, start by evaluating your current architecture against the four limitations described in this post. These are anomaly blind spots, detection latency for fraud, static threshold scalability, and cost at high cardinality. From there, consider whether a declarative detection layer (separating rule definition from execution) could accelerate your team’s ability to ship new alerts without infrastructure changes. For a hands-on starting point, explore the Amazon MSK Labs workshop.
To learn more about Amazon MSK, visit the documentation.
Marketing teams running large-scale campaigns often send the same message across SMS, WhatsApp, and email regardless of how each customer engages or how many messages they’ve already received that week. This pattern wastes budget on channels customers ignores and pushes promotional content toward frustrated or message-fatigued customers. A MarketingSherpa study found that 45% of consumers who unsubscribe from email marketing cite messages being too frequent as the reason. Over-messaging therefore erodes the audience a brand has paid to acquire. This post shows how to build a campaign orchestrator on AWS End User Messaging and Amazon Bedrock. The orchestrator predicts the best channel for each customer, adapts content per channel, and holds back messages to fatigued or unhappy customers.
In this post, we describe the following capabilities for enterprise marketing teams:
Channel prediction that selects SMS, WhatsApp, or email for each customer based on engagement history
Content adaptation that takes a single campaign brief and produces channel-appropriate variants: a 160-character SMS, a longer WhatsApp template message, and an HTML email
Sentiment-aware suppression that holds back promotional messages when a customer’s stored sentiment score is negative
Frequency tracking across channels that lowers send rate when a customer shows disengagement signal
Natural-language campaign launch that turns a typed instruction such as “Send the Andaman package to Mumbai customers who haven’t booked in six months” into a segmented, channel-routed send
Amazon Bedrock model access granted for an Anthropic Claude model in your AWS Region
(Optional) An Amazon SageMaker AI endpoint for channel prediction. The orchestrator calls the endpoint when it’s configured and falls back to the customer’s stored preferred channel otherwise.
Solution overview
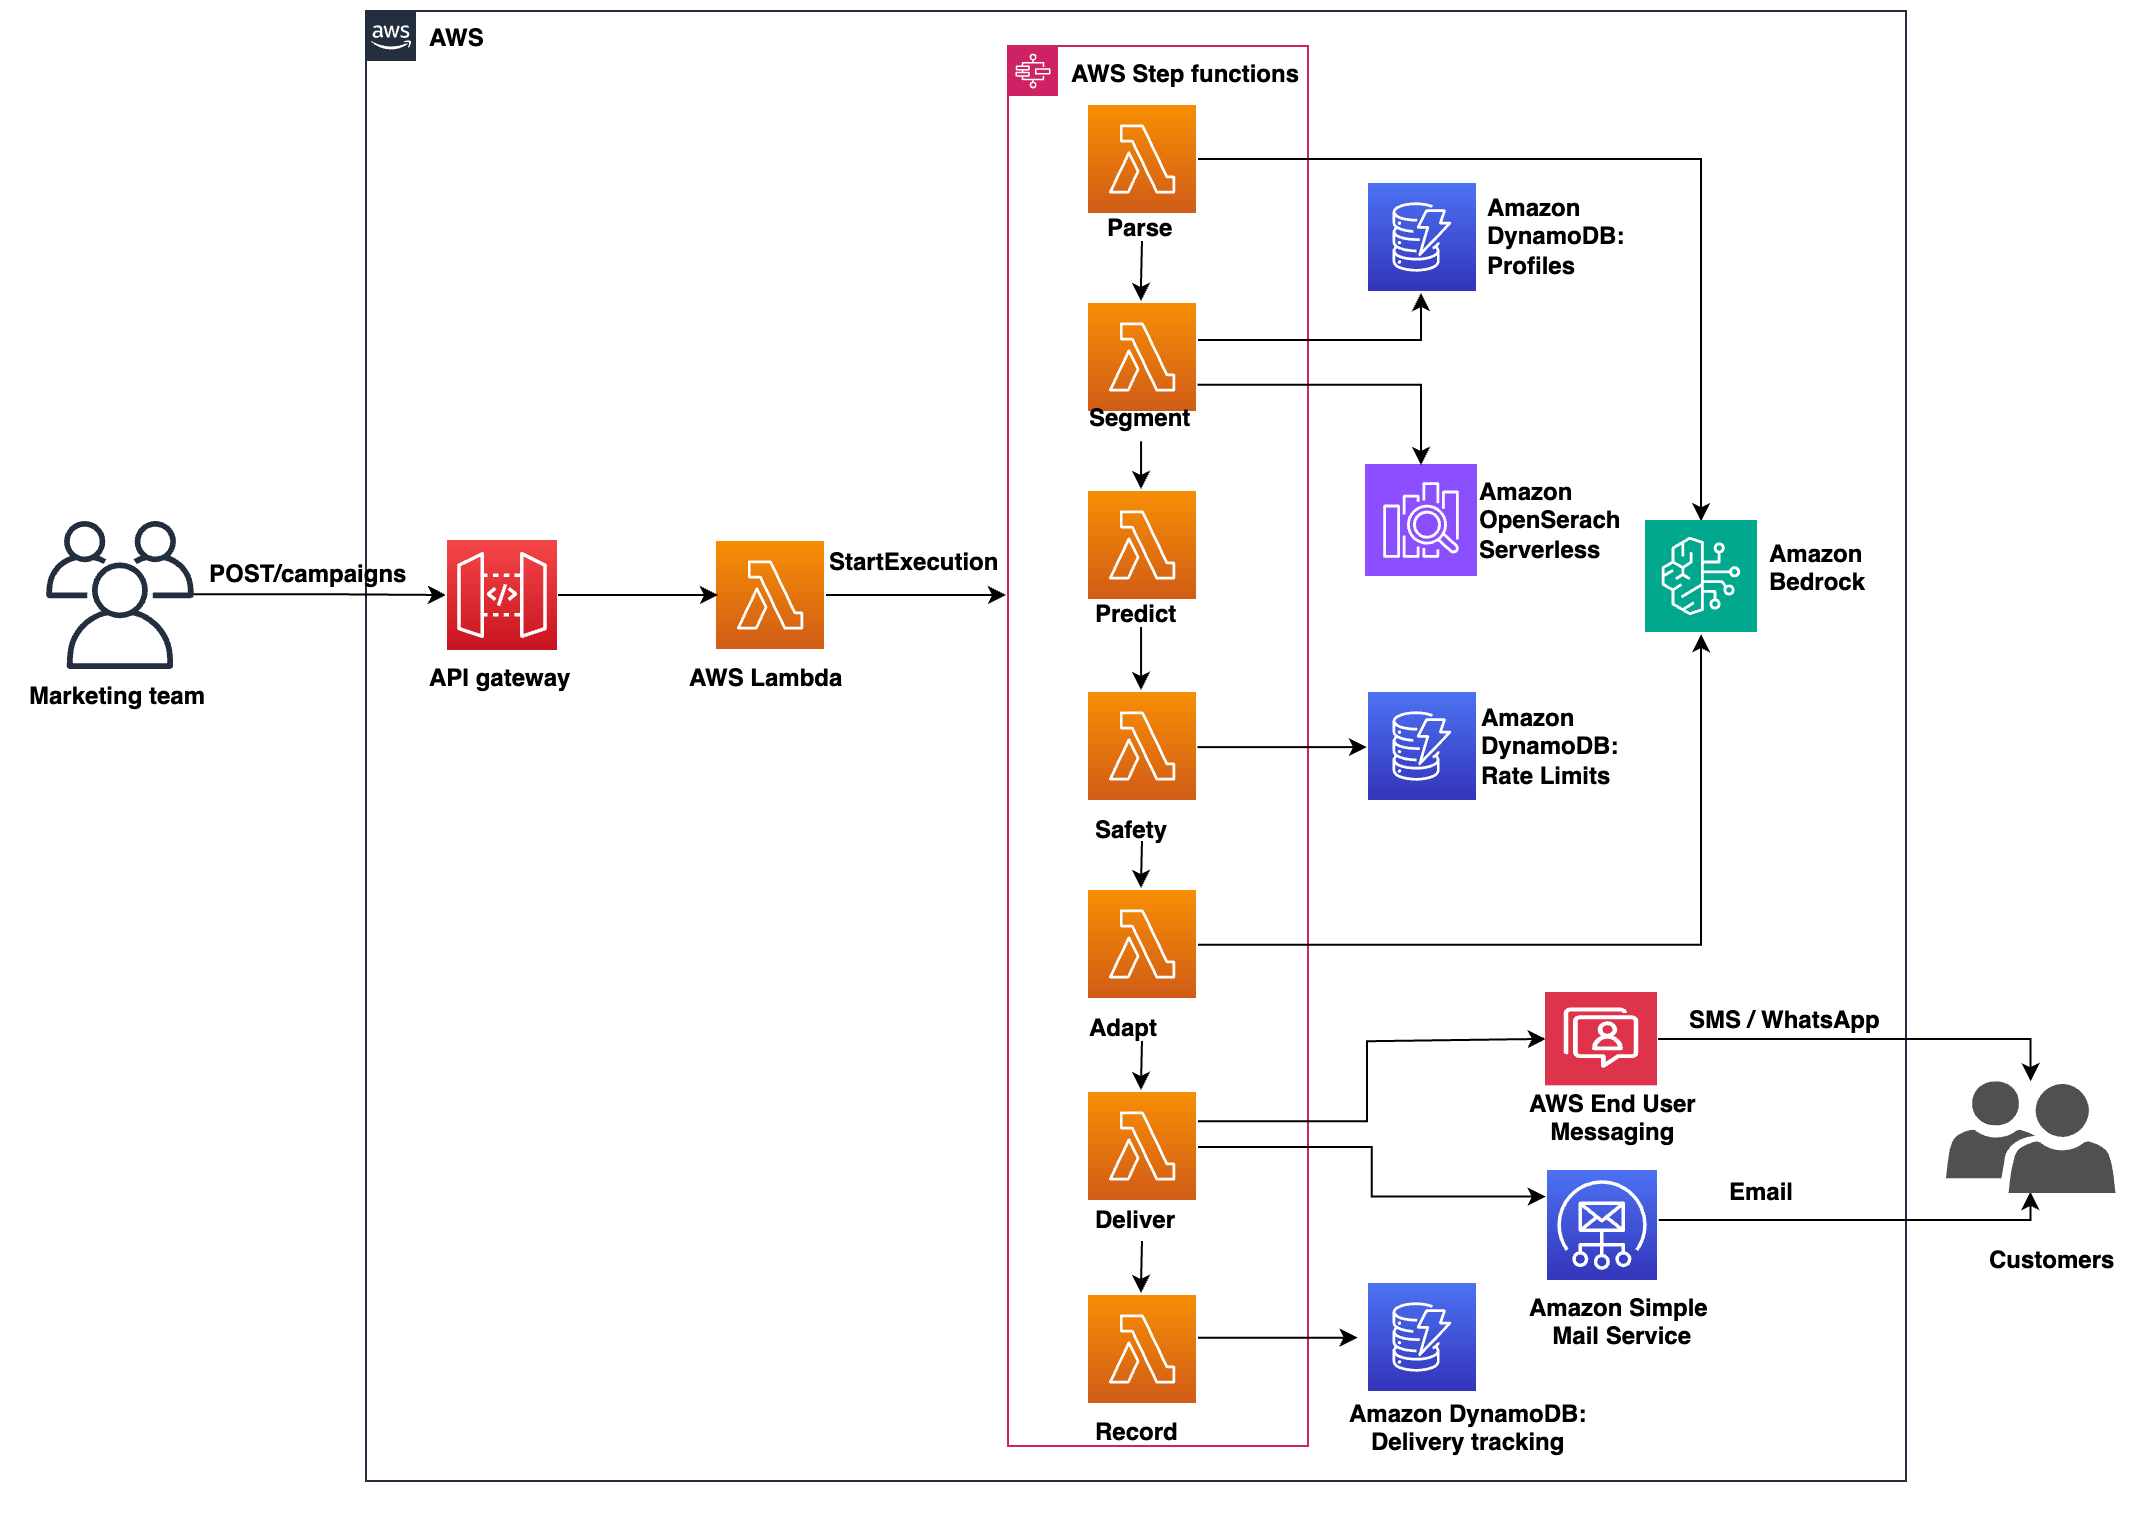
A marketer types a plain-language instruction into the campaign launcher. Amazon API Gateway forwards the instruction to an AWS Lambda function, which starts an AWS Step Functions state machine. The state machine walks the campaign through seven stages. Each stage moves the campaign closer to dispatching the right message on the right channel. The stages read and write customer state in Amazon DynamoDB and call Amazon Bedrock for language tasks. The final stage dispatches messages through AWS End User Messaging or Amazon Simple Email Service (Amazon SES).
When you turn on semantic segmentation, the state machine also queries an Amazon OpenSearch Serverless collection. The collection holds customer embeddings.
To deploy the sample in your account, refer to the GitHub repository.
Figure 1 shows the campaign orchestration system.
Message processing
When a marketer submits an instruction, the launcher Lambda function starts a Step Functions execution. The state machine then runs the stages in order. Each stage reads the output of the previous one, applies its own logic, and passes its result forward. The state machine retries transient failures within a stage, so a Bedrock throttle or a DynamoDB timeout doesn’t restart the whole campaign. A choice state redirects the workflow straight to the recording stage when no customers pass the safety check, so empty campaigns skip the content adaptation step. This decoupled design gives operators three things:
If one stage fails, the workflow retries that stage without rerunning earlier work
You can add new stages — for example, a translation step — without changing the others
The system scales with campaign volume
AI conversation engine
Amazon Bedrock does two distinct things in the orchestrator, and they happen at different stages. The parse stage runs first. It takes the marketer’s plain-language instruction and asks the model to return a small JSON object. The JSON has fields such as location, package, age range, and a short semantic query when the instruction implies a lifestyle or affinity. That JSON is what every downstream stage works against, so the parse output sets the shape of the campaign.The parse stage sends the following prompt to Anthropic Claude on Bedrock through the InvokeModel API:
You parse marketing campaign instructions into structured fields.

Instruction:
{instruction}

Return JSON with these fields:
- "sku" (string or null): product SKU or package name
- "location" (string or null): city or region
- "category" (string or null): one of "Electronics", "Travel", "Apparel", "Home"
- "min_age" (integer or null), "max_age" (integer or null)
- "min_purchases" (integer or null)
- "lookback_days" (integer or null)
- "has_cart_items" (bool or null)
- "semantic_query" (string or null): free-text lifestyle/affinity descriptor

Output ONLY the JSON object, no prose.
For the instruction “Send the Andaman package to budget-conscious families in Mumbai”, the model returns:
The adapt stage runs later, after segmentation and safety. It takes a single campaign brief and asks Bedrock to produce one variant per channel: a 160-character SMS, a longer WhatsApp template message, and an HTML email. The model never sees customer-level data at this point; the brief and the channel are the only inputs.The orchestrator stores one prompt per channel. The SMS prompt enforces a hard character limit; the WhatsApp prompt allows a longer message; the email prompt asks for structured HTML:
# SMS
Write a single SMS for the campaign brief below. Hard limit: 160 characters.
No emojis, no links unless the brief explicitly includes one. Plain text only.

# WhatsApp
Write a WhatsApp message for the campaign brief below. Up to 1024 characters.
Friendly tone, optional emoji where natural.

# Email
Write an HTML email body for the campaign brief below. Include a single <h1>,
two short paragraphs, and a call-to-action link placeholder {{CTA_URL}}.
No <html> or <body> wrappers.
Each prompt is formatted with the campaign brief and sent to Bedrock; the response becomes that channel’s variant for every approved customer in the segment.
The safety stage runs after the parse stage and before the adapt stage, and it is rule-based rather than model-based. It reads each customer’s stored sentiment score and rolling send count from DynamoDB, and drops customers below the sentiment threshold (default -0.3) or above the fatigue limit. The fatigue limit is a per-customer count of sends over a rolling window, for example five sends in the previous seven days. You set the fatigue window and the sentiment threshold as Step Functions input parameters. You populate the sentiment score upstream. For example, you can run a daily Amazon Comprehend Custom Classification job that scores recent support transcripts and writes the result back to the customer record.
The fatigue check reads the customer’s recent send timestamps from the rate-limits table and counts the entries inside the rolling window:
NEGATIVE_THRESHOLD     = Decimal("-0.3")     # configurable
MAX_MESSAGES_PER_WINDOW = 5
WINDOW_SECONDS         = 7 * 24 * 60 * 60     # 7 days

def _is_fatigued(customer_id):
    item = _rate_limits.get_item(Key={"limiter_key": f"customer:{customer_id}"}).get("Item")
    if not item:
        return False
    cutoff = int(time.time()) - WINDOW_SECONDS
    recent = [t for t in item.get("recent_sends", []) if int(t) >= cutoff]
    return len(recent) >= MAX_MESSAGES_PER_WINDOW
Each successful send writes its timestamp into the customer’s recent_sends list, so the next campaign sees an up-to-date fatigue count without a separate ETL step.
Orchestration
Each stage in the campaign workflow is a small AWS Lambda function. The state machine invokes them in sequence: parse the instruction, segment customers, predict channels, check safety, adapt content, deliver messages, and record results. The predict stage reads each customer’s per-channel engagement history from DynamoDB and picks the channel with the highest historical engagement rate. When you wire an Amazon SageMaker AI endpoint into the stack, the stage calls that endpoint instead and uses its score as the channel ranking signal.The state machine, not the functions, owns the control flow. New stages (for example, a translation step before adapt content) can be inserted without changing the existing handlers. The Step Functions definition lives in statemachine/campaign_orchestrator.asl.json. Refer to it in the GitHub repository for the exact state graph and retry policy.
Semantic search
Consider a marketer who types “Send the Andaman package to budget-conscious families interested in beach vacations.” A keyword filter against the customer table won’t match a profile tagged “economy package, kid-friendly, coastal”, because the words don’t overlap even though the meaning does. To bridge that gap, the seed script embeds each customer profile with Amazon Titan Text Embeddings v2 and writes the vector into an OpenSearch Serverless Vector search collection. The segment stage then embeds the marketer’s phrasing at query time and runs a k-nearest-neighbor search against the collection.
The orchestrator intersects those matches with the structured DynamoDB filter. The final segment respects both the hard constraints (location, age, recency) and the soft ones (lifestyle, affinity). OpenSearch Serverless scales the collection’s compute units to zero when idle, so this capability adds near-zero cost when no campaigns run.
Deployment
To deploy the sample in your AWS account, clone the GitHub repository and run the SAM-based deploy script:
git clone https://github.com/aws-samples/sample-ai-campaign-orchestrator.git
cd sample-ai-campaign-orchestrator
./scripts/deploy.sh --guided
The script prompts you for an AWS Region, a stack name, and the orchestrator parameters (your WhatsApp phone number ID and optional SES sender). It then runs sam build followed by sam deploy, and prints the API endpoint and stack outputs when the deployment finishes.
Test the solution
After the stack finishes deploying, seed the customer profiles table with one sample customer and run a campaign against it:
Then submit a campaign instruction to the API endpoint that the deploy script printed:
curl -X POST $ENDPOINT -H 'content-type: application/json' \
  -d '{"instruction": "Send the Andaman package to Mumbai customers"}'
From here you can:
Watch the campaign execution in the AWS Step Functions console.
Query the delivery tracking table in Amazon DynamoDB to see which customers the safety stage approved or suppressed, and which channel the orchestrator picked for each.
Check the recipient’s phone for the WhatsApp template message that the deliver stage sent.
Sample conversation
The recording in this section shows a marketer using the campaign launcher to send an Andaman travel promotion to a Mumbai segment. It opens with the marketer typing the natural-language instruction and the parse stage extracting structured filters. The segment stage then matches customers in DynamoDB. The safety stage suppresses a customer with a low sentiment score. The predict stage assigns a channel per remaining customer. The recording ends with the adapt stage producing one message variant per channel and the deliver stage dispatching them through AWS End User Messaging.
Clean up
To avoid incurring future charges, delete the resources you created. The sample includes a cleanup script in the GitHub repository. Run ./scripts/cleanup.sh to empty the deployment bucket and delete the stack. The stack deletion removes the AWS Step Functions state machine, AWS Lambda functions, Amazon DynamoDB tables, and (when configured) the Amazon OpenSearch Serverless collection.
Conclusion
You can combine AWS End User Messaging, Amazon Bedrock, and AWS Step Functions to build a campaign orchestrator. The orchestrator routes each message to the channel a customer is most likely to open. It also holds back sends to fatigued or unhappy customers.
The same pattern fits other business-initiated messaging workflows where per-recipient channel and content decisions matter. Examples include transactional banking notifications, appointment reminders, and logistics status updates. To deploy the sample in your account, refer to the GitHub repository. To learn more about AWS End User Messaging, refer to the service documentation.
If you’re applying this pattern, start with the safety check and frequency tracking. Those two stages reduce the risk of damaging customer relationships and produce the engagement data that channel prediction depends on. Once that data is in place, add the prediction and content adaptation stages. Use this implementation as a reference for production messaging on AWS.
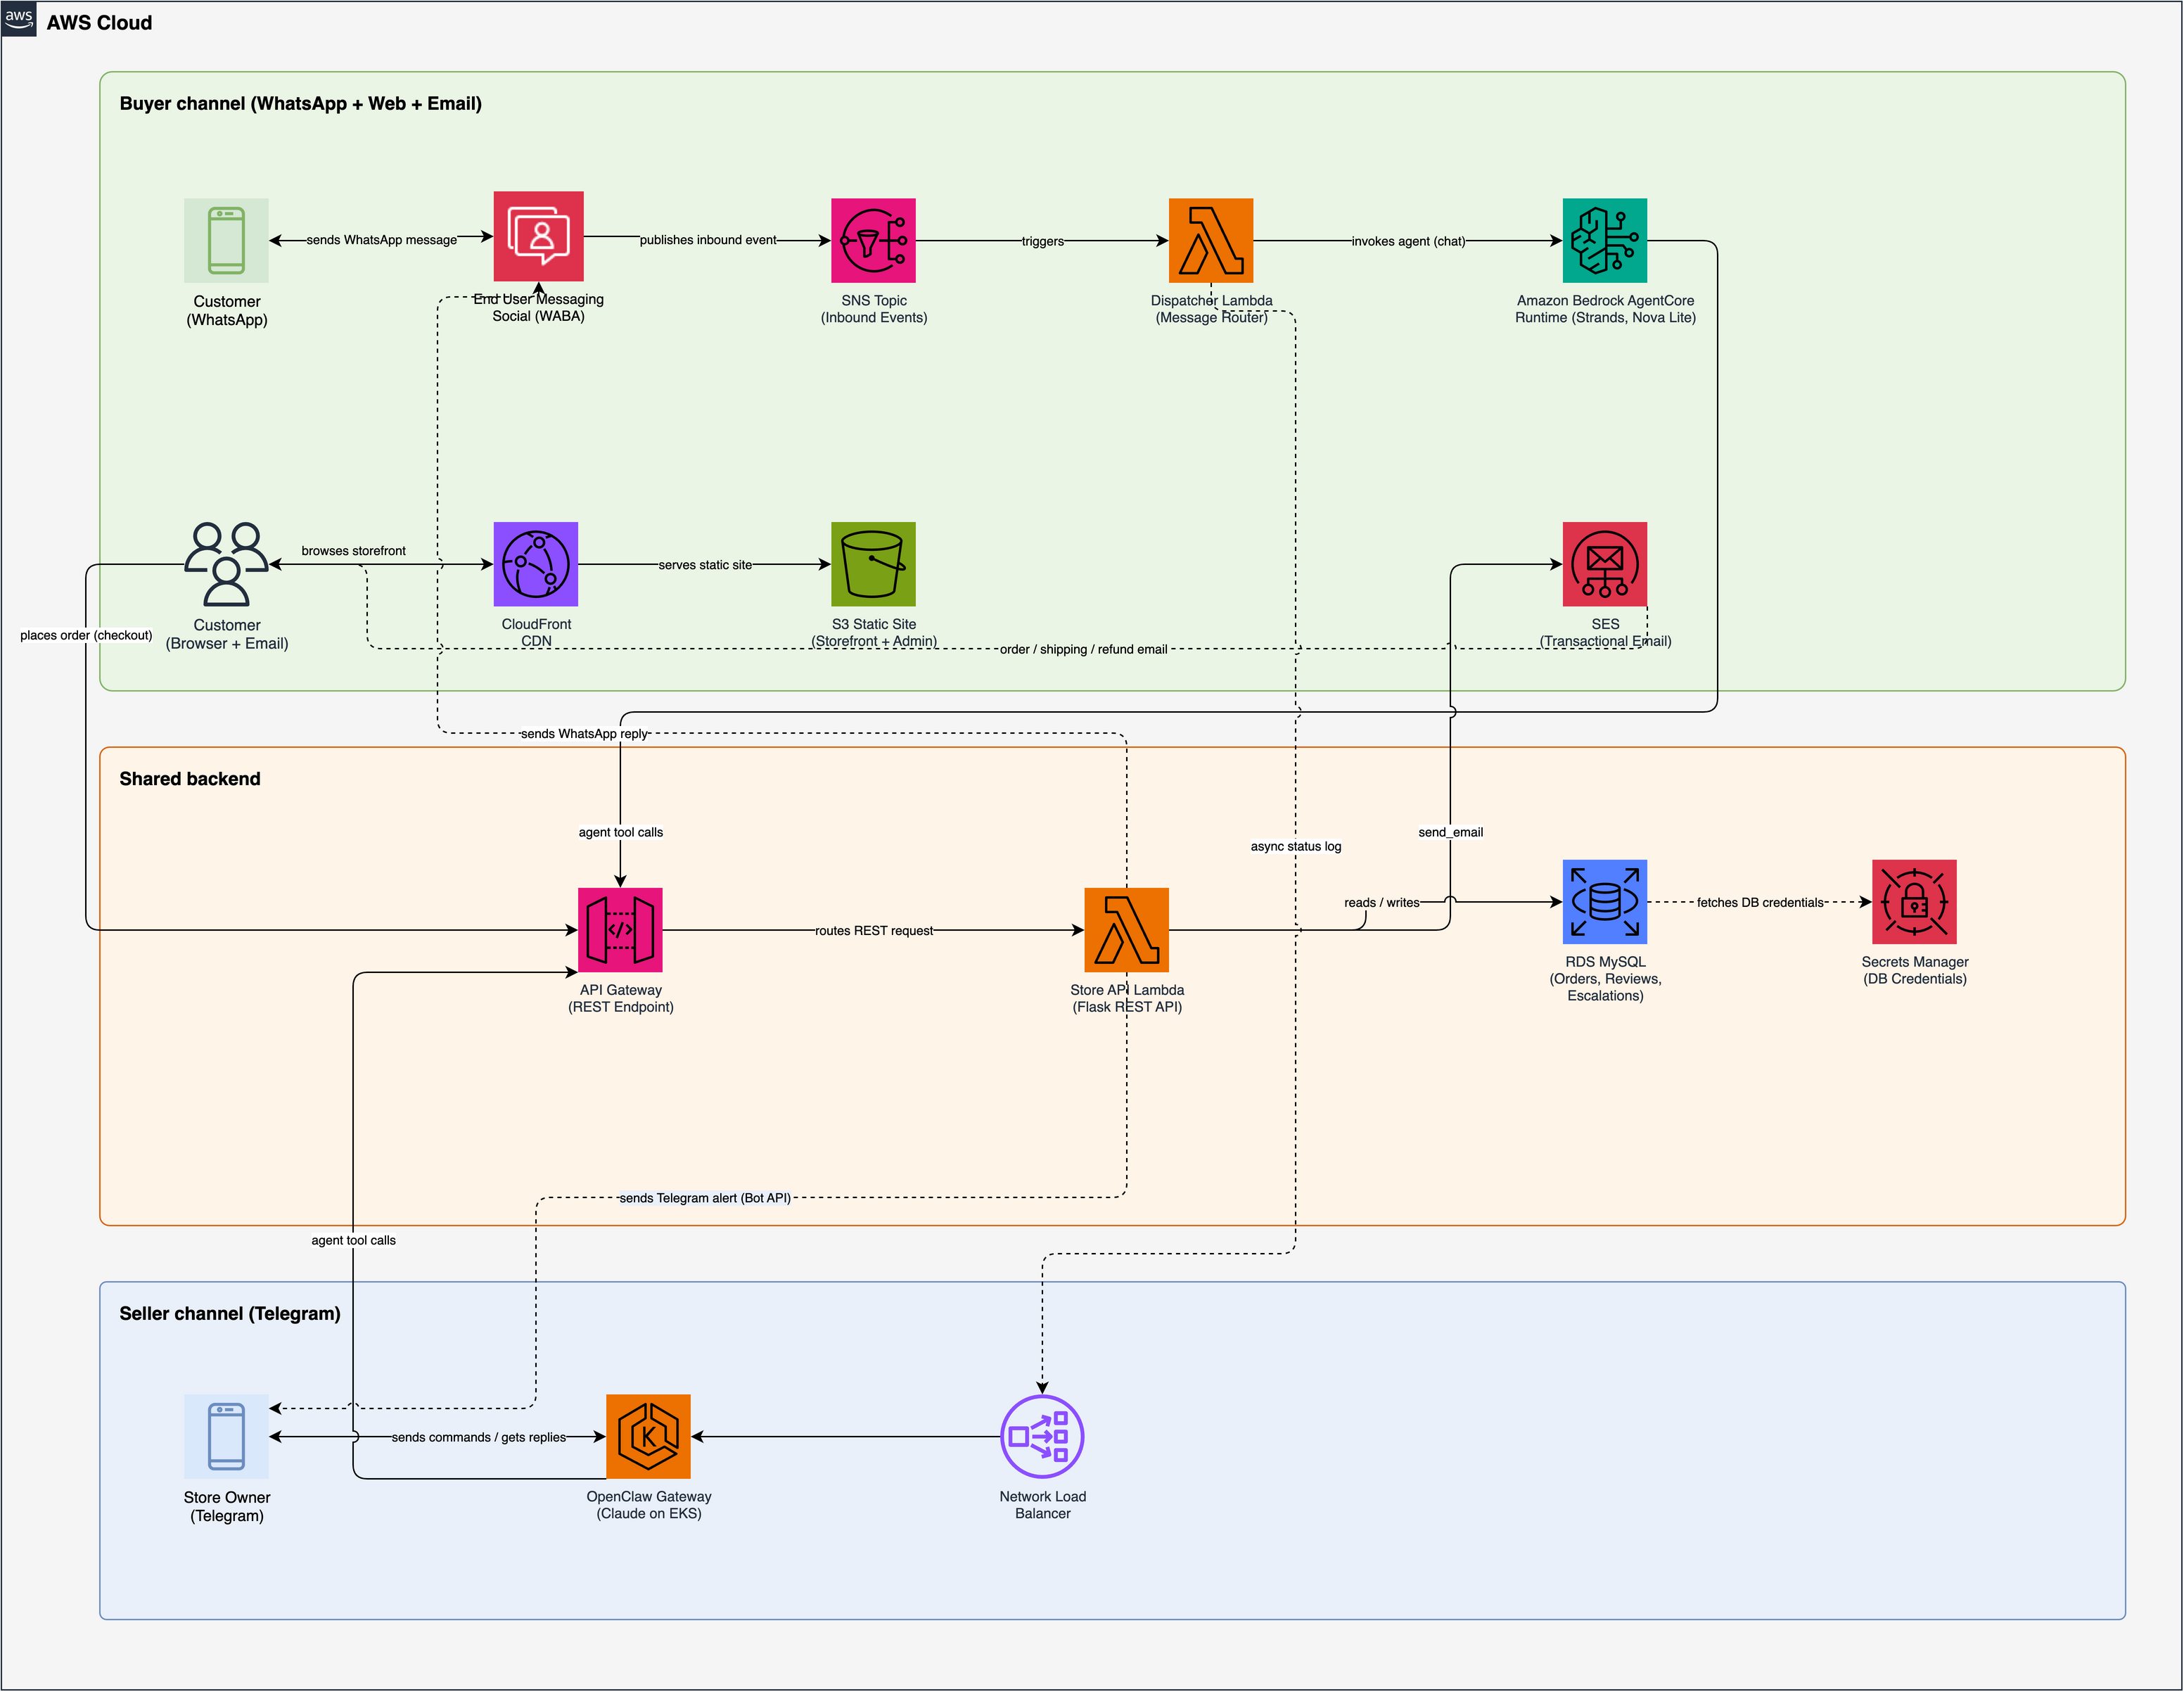
In this post, we walk through Claw Boutique, an open-source reference architecture that connects a web storefront, WhatsApp, email, and Telegram into a single OpenClaw-driven ecommerce experience on AWS. Buyers interact through WhatsApp and a web store. The shop owner manages everything from Telegram, where an artificial intelligence (AI) agent processes restock, refund, and order commands.
The architecture separates concerns into three channels that share a common Store API and database.
Figure 1 – Claw Boutique architecture on AWS
Buyer channel (WhatsApp): Inbound WhatsApp messages arrive through AWS End User Messaging Social, which provides a managed WhatsApp Business API integration. Messages publish to an Amazon Simple Notification Service (Amazon SNS) topic, which triggers a Dispatcher AWS Lambda function. The dispatcher invokes a Strands Agent hosted on Amazon Bedrock AgentCore Runtime, running Amazon Nova Lite for real-time, tool-calling conversations. AgentCore Memory provides session continuity across messages. The agent can look up products, check order status, escalate issues, and send replies back through WhatsApp.
Seller channel (Telegram): The store owner receives stock alerts, review escalations, and order notifications on Telegram. An AI agent runs on Amazon EKS via the OpenClaw gateway. The owner replies with natural language commands such as “restock hoodies” or “apologize to the buyer,” and the agent runs the appropriate Store API calls.
All three channels converge on a single Store API Lambda function (Python/Flask) backed by Amazon Relational Database Service (Amazon RDS) for MySQL. Amazon Simple Email Service (Amazon SES) sends transactional email messages for order confirmations, shipping updates, and refund notices.
How it works: The order lifecycle
A single order touches the web storefront, WhatsApp, email, Telegram, and the admin dashboard. Here is the full flow.
1. Place an order
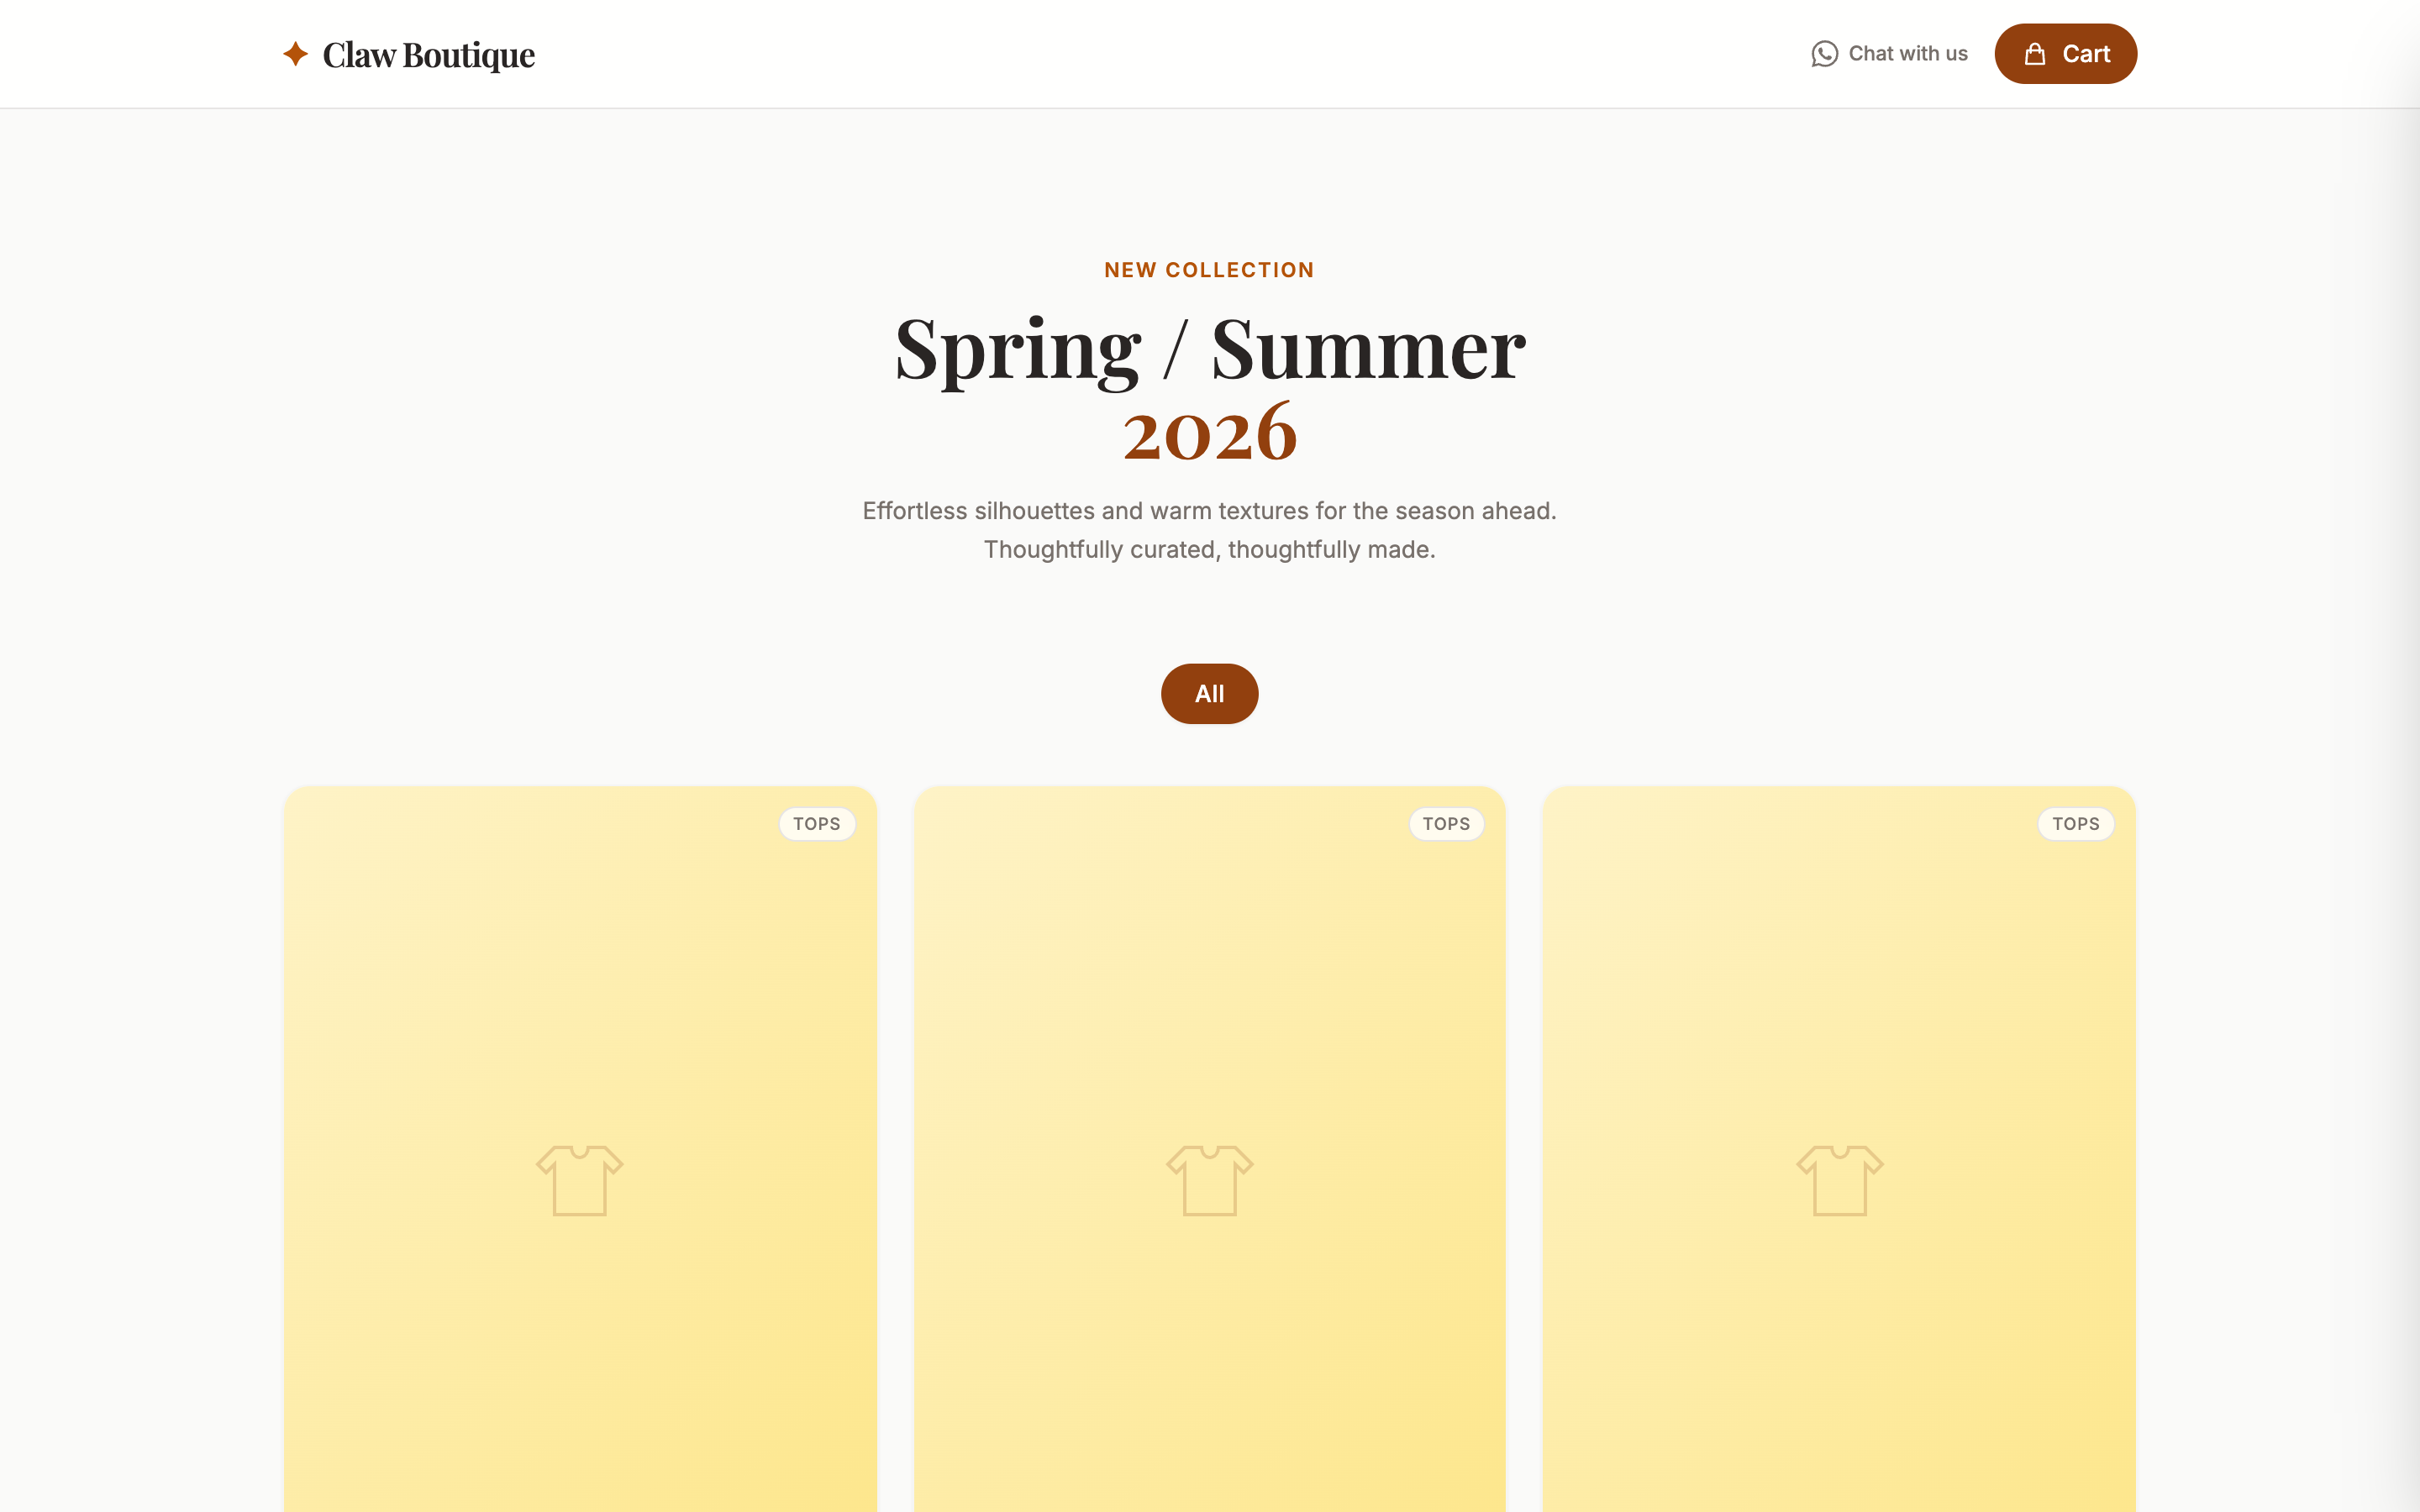
You visit the storefront, add items to the cart, and check out. The Store API creates the order in Amazon RDS and returns an order number.
Figure 2 – The Claw Boutique storefront
2. Order confirmation on WhatsApp and email
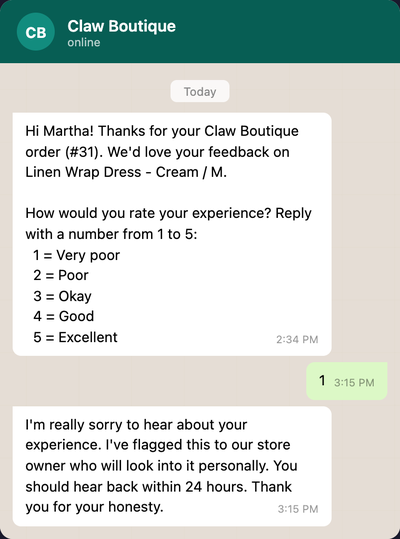
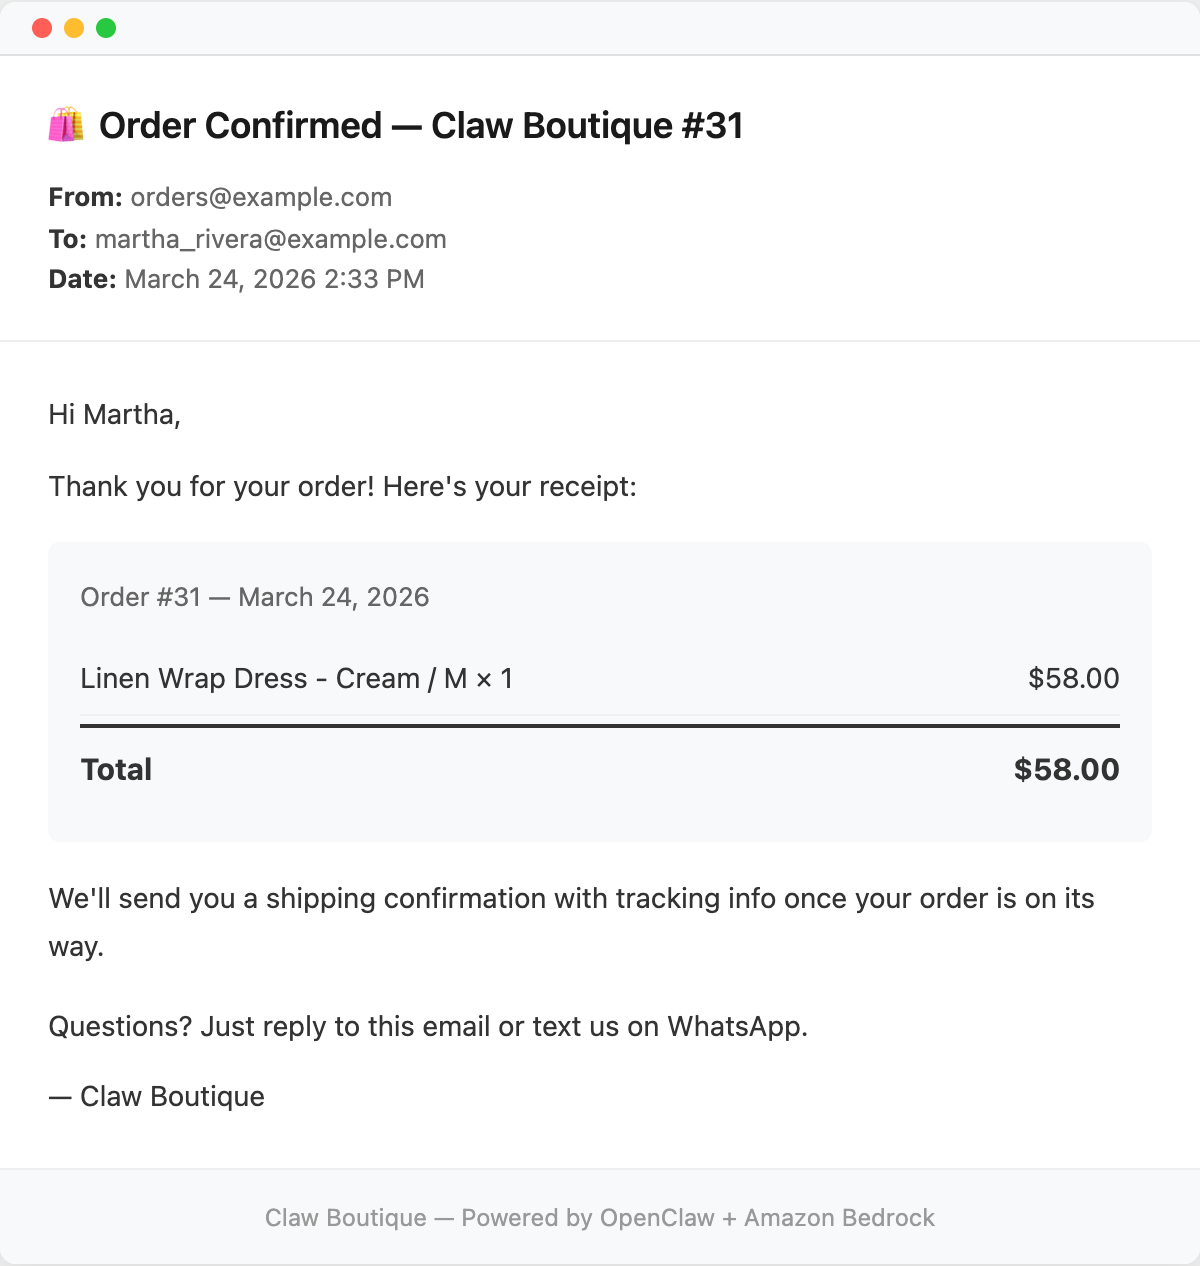
Two things happen right after checkout. The buyer receives a WhatsApp message with the order number, items, and total, followed by a feedback survey asking them to rate their experience from 1 to 5. At the same time, Amazon SES sends a confirmation email with the same order details.
Figure 3 – WhatsApp order confirmation and feedback survey
Figure 4 – Order confirmation email via Amazon SES
3. Stock alert on Telegram
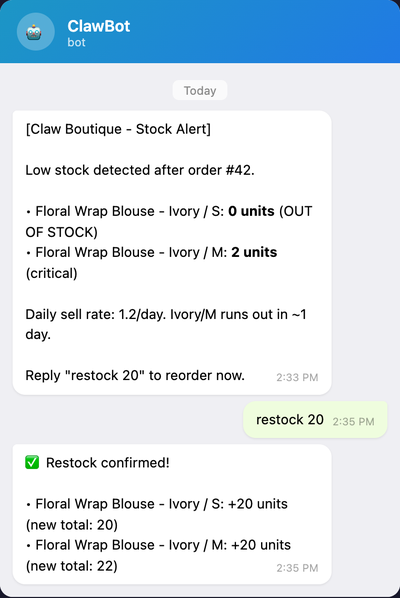
Every purchase triggers a stock check. If any item is out of stock, running low (fewer than 5 units), or projected to sell out within 7 days, the seller gets a Telegram alert with current stock levels and sell-through rates. The seller can reply with a command such as “restock hoodies 20” and the AI agent runs it.
Figure 5 – Telegram stock alert with restock command
4. Negative feedback triggers an escalation
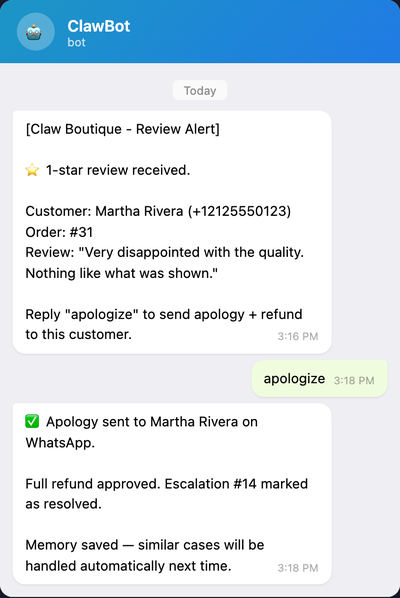
The buyer replies “1” to the WhatsApp survey. The Store API creates an escalation record and sends the seller a Telegram alert with the buyer’s name, phone number, rating, and review text.
Figure 6 – Telegram review escalation alert
5. Seller resolves the issue from Telegram
The seller replies “apologize” on Telegram. The AI agent looks up the unresolved escalation and takes four actions: sends a WhatsApp apology to the buyer, sends a refund confirmation email via Amazon SES, marks the order as “refunded” in the database, and resolves the escalation. If there are multiple open escalations, the agent lists them and asks which one to resolve.
6. Admin dashboard
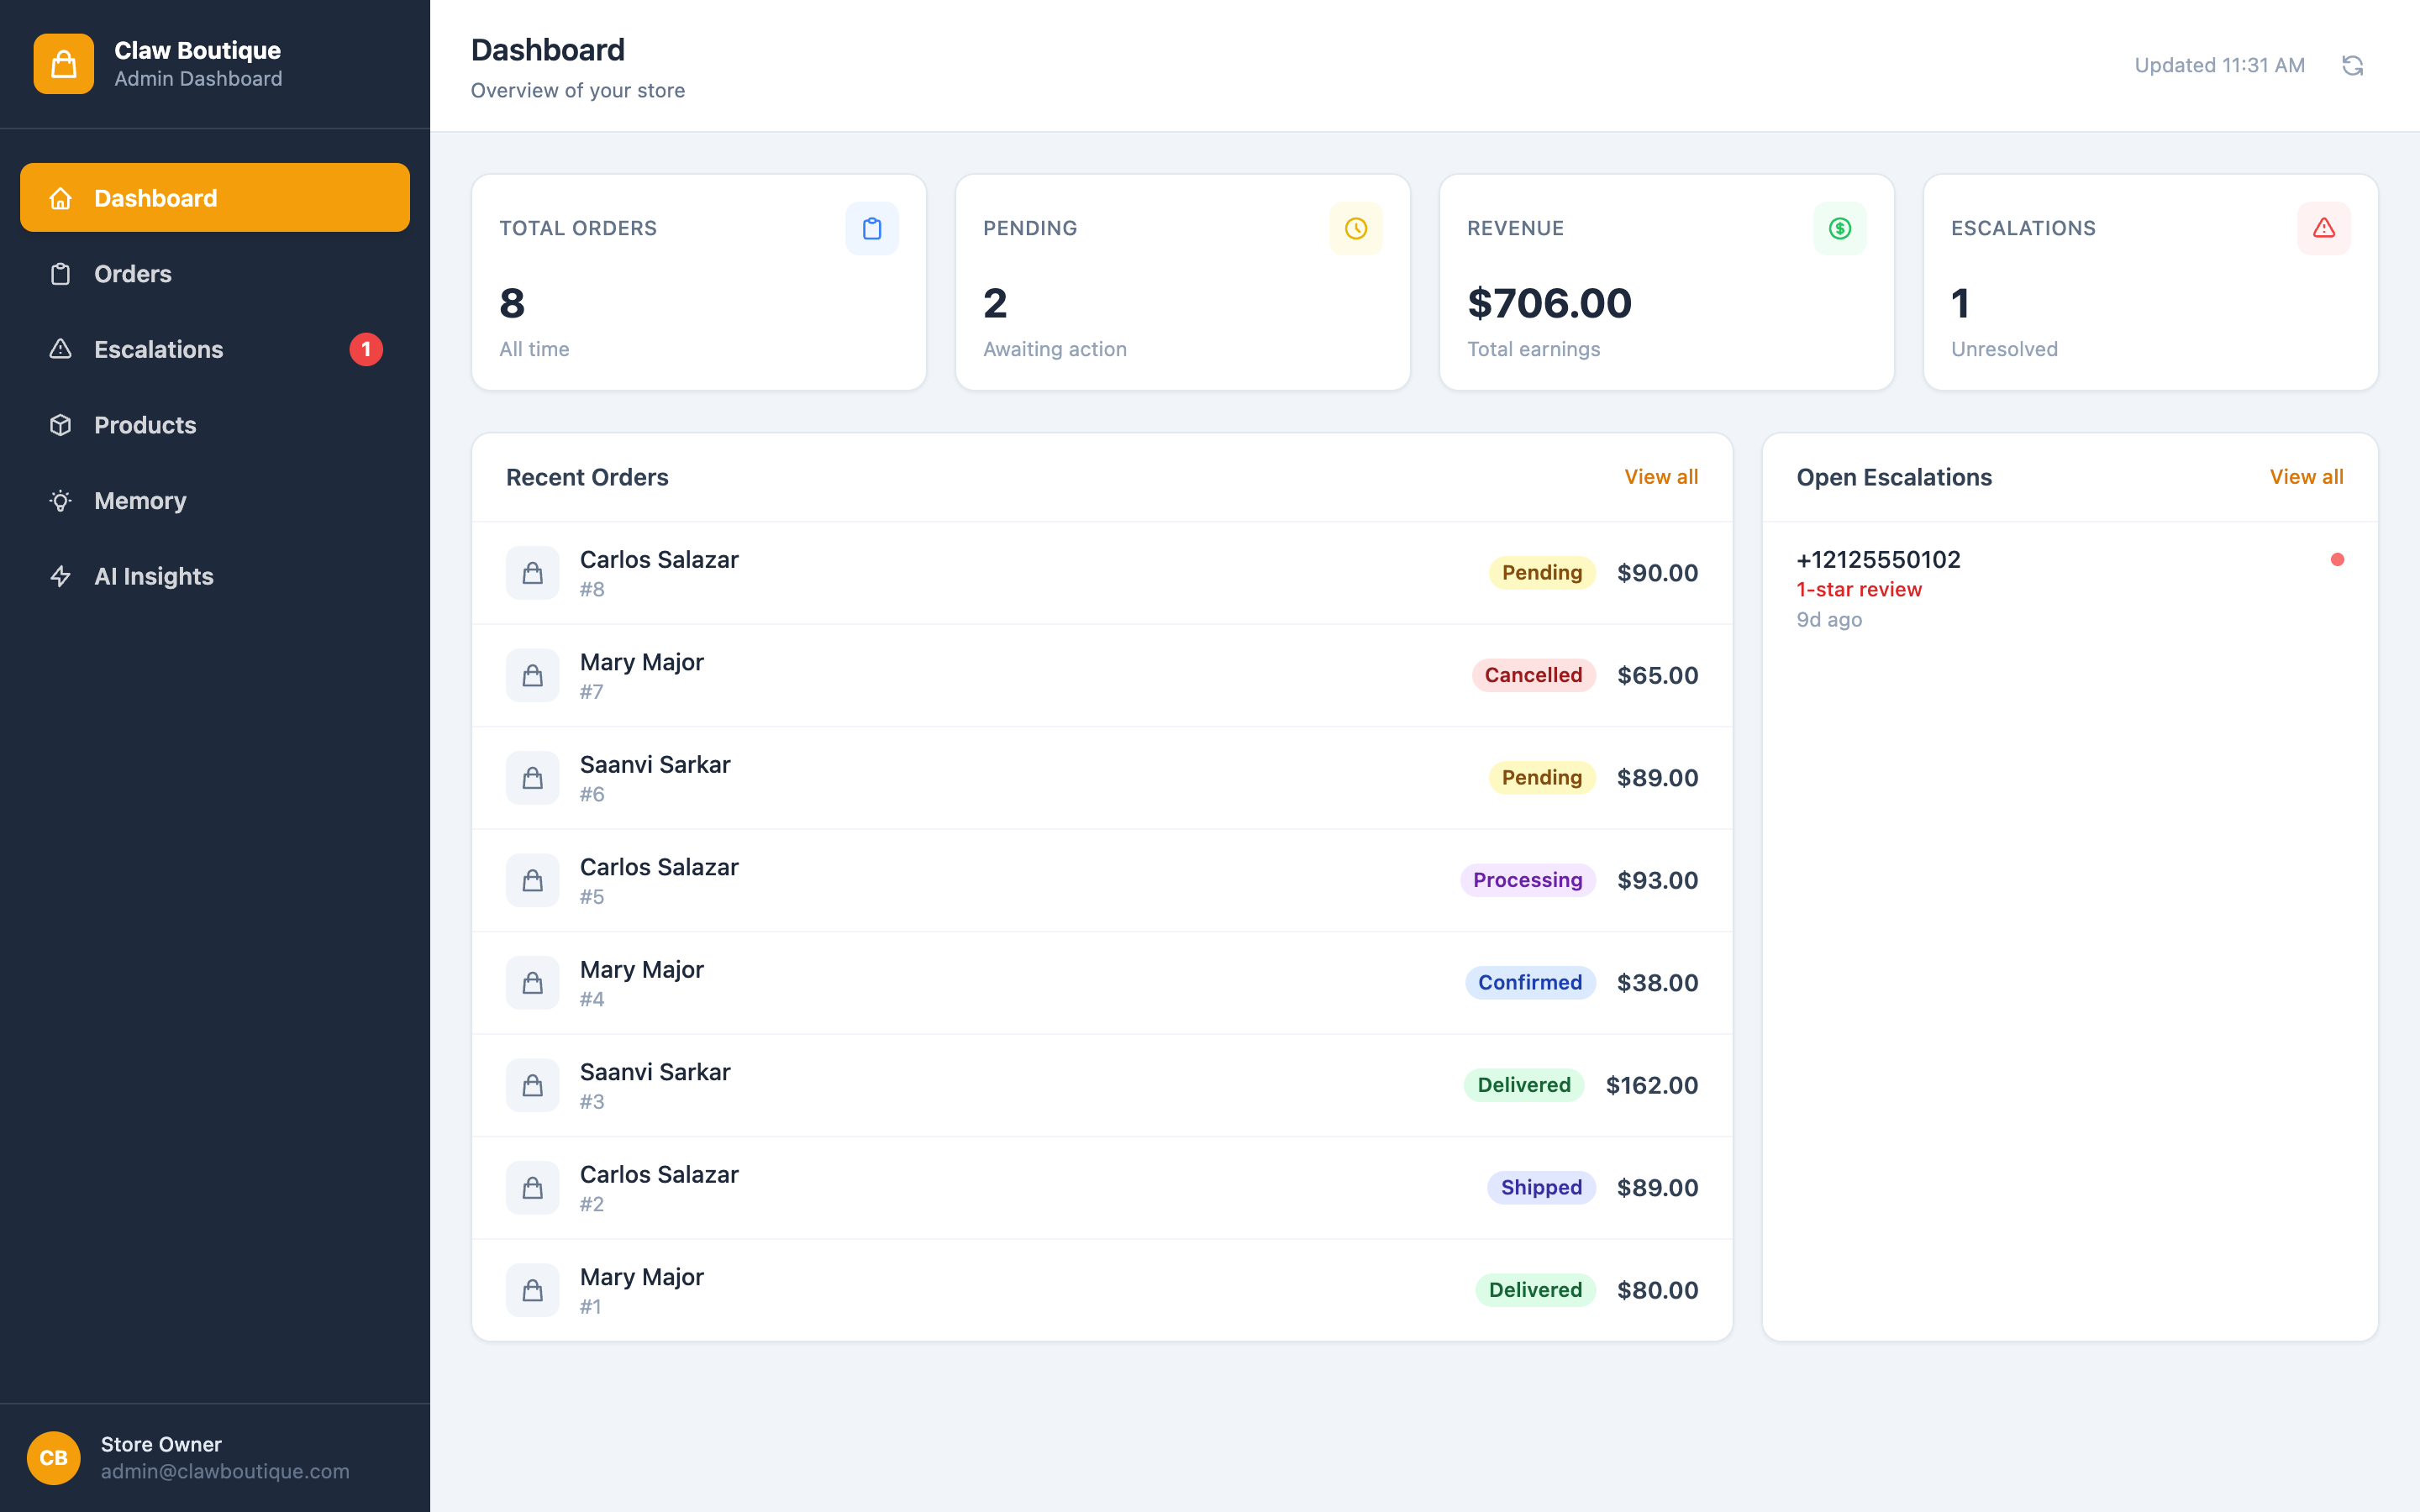
The seller can also open the admin dashboard to view orders (now showing “refunded” status), escalation history, stock levels, and AI-generated business insights based on order patterns and buyer feedback.
Figure 7 – Admin dashboard with orders and insights
Ordering directly through WhatsApp
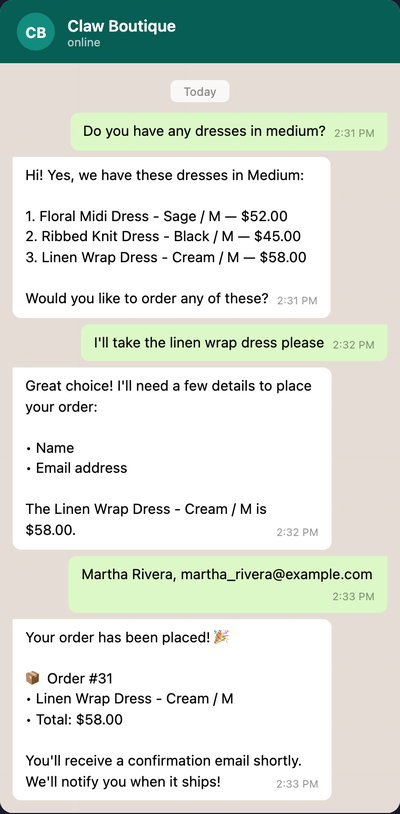
Buyers can also browse and order by texting the WhatsApp business number directly. The Strands Agent on AgentCore manages the full conversation: showing available products, checking order status, answering product questions, and escalating issues to the store owner.
Figure 8 – Ordering through WhatsApp via Amazon Bedrock AgentCore
Why two AI models?
Claw Boutique uses two AI models for different purposes, each chosen for the characteristics that matter most in its channel.
Amazon Nova Lite (via Amazon Bedrock AgentCore) for the buyer channel: Buyer-facing WhatsApp interactions need to be fast and cost-effective. Amazon Nova Lite provides sub-second responses with reliable tool calling at a fraction of the cost of larger models. AgentCore Runtime hosts the agent container, while AgentCore Memory manages conversation history per buyer phone number. The Strands Agents SDK handles tool definitions, orchestration, and model interaction with minimal boilerplate.
AI agent (via OpenClaw on Amazon EKS) for the seller channel: The seller channel involves more complex tasks: interpreting ambiguous commands, managing multi-step workflows (such as resolving escalations that span WhatsApp, email, and the database), and generating business insights. The model’s reasoning capabilities are well suited for these. OpenClaw provides the gateway, tool execution, and memory management layer.
This approach keeps buyer-facing latency low and costs predictable, while giving the seller access to deeper reasoning when managing the business.
Prerequisites
Before you deploy, make sure you have the following:
AWS Command Line Interface (AWS CLI) configured with credentials.
The entire stack deploys with AWS CDK. A single cdk deploy command provisions the Amazon Virtual Private Cloud (Amazon VPC), Amazon EKS cluster, Amazon RDS database, Lambda functions, Amazon API Gateway, Amazon CloudFront distribution, Amazon S3 bucket, Amazon SNS topic, and all AWS Identity and Access Management (IAM) roles and security groups. AWS CDK also runs database initialization (schema and seed data), Docker image build, Amazon Elastic Container Registry (Amazon ECR) push, and Amazon EKS deployment.
Configuration values (Telegram token, WhatsApp IDs, Amazon SES email) go into a CDK context file. Cold deploy takes about 25-30 minutes.
You can find the full source code and deployment instructions in the GitHub repository.
Cleaning up
To avoid ongoing charges, delete the resources created in this walkthrough when you’re done experimenting. Run the following command from the cdk/ directory:
cd cdk && npx cdk destroy
This removes the Amazon EKS cluster, Amazon RDS database, Lambda functions, and all other resources created by the stack. No context values are needed for destroy.
Conclusion
In this post, we showed how to build an ecommerce bot using OpenClaw and Amazon Bedrock AgentCore. By combining AWS End User Messaging Social for WhatsApp, Amazon Bedrock AgentCore Runtime for real-time buyer conversations, and Amazon EKS for a seller-side AI agent, you can create a system where buyers order through the channels they already use, and store owners manage their business from a single Telegram chat.
The project is open source and deploys with a single AWS CDK command. You can use it as a starting point and adapt it to your own product catalog, messaging channels, and business logic.
AWS Builder Center turned one year old last week. Launched on July 9, 2025, the platform has grown from a community hub with Wishlist voting, community profiles, and a toolbox into a full ecosystem with sandbox environments, workshops, Spaces, and a Builders’ Library. To mark the anniversary, Rick Suttles published a full feature timeline covering everything shipped over the past year: AWS Capabilities by Region (1,500+ services across 37 Regions), Spaces for community-created groups, workshops with category and complexity filters, badges and streaks, article series, view counts, saved items, student status, availability notifications, sign-in with GitHub and Amazon, and sandbox environments.
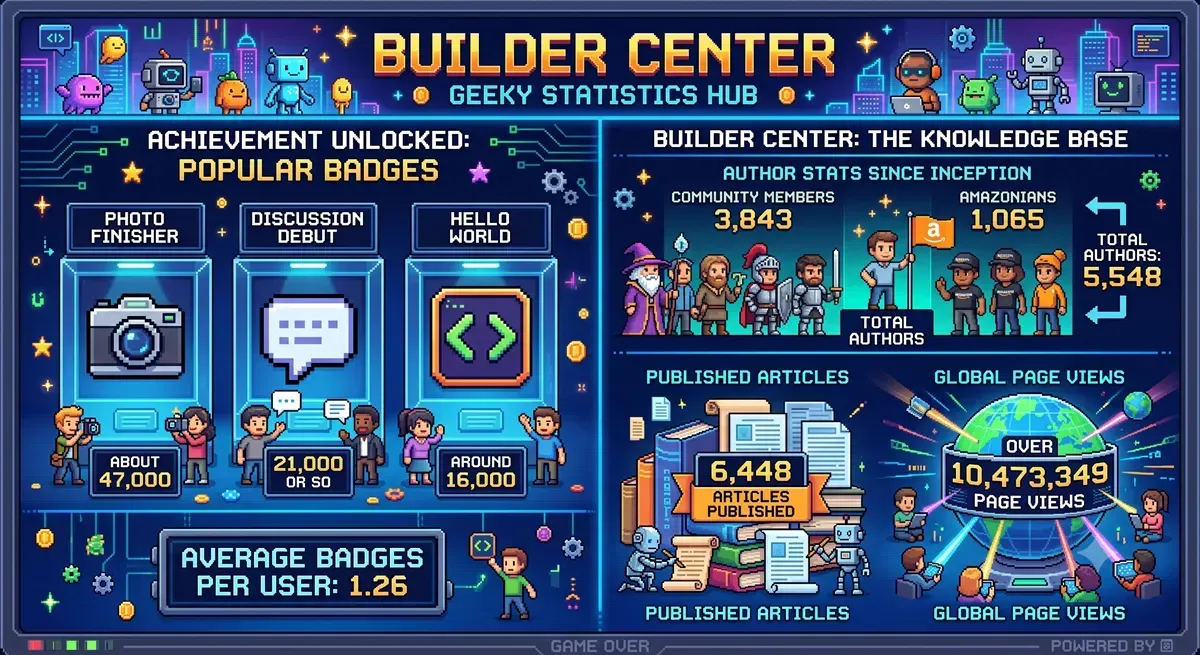
Jeff Barr published a retrospective summarizing Builder Center’s first year. Since launch, 5,548 authors have published 6,448 articles with more than 10.4 million page views combined. Builders have earned 99,226 badges since the badge system launched in March 2026. Community members have submitted 565 wishes, 10 of which have shipped with another 20 on the near-term roadmap.
The week’s headline addition is Sandbox Environments by Rick Suttles. Sandboxes give you a free, pre-provisioned AWS account to complete a workshop exercise. Each environment is active for 8 hours, after which the account and all its resources are automatically de-provisioned. You can have one active sandbox at a time and request one per week. No personal AWS account, credit card, or manual cleanup required.
Last week’s launches Here’s what else happened this week.
AWS Security Hub introduces Network Scanning – Security Hub introduced Network Scanning, a capability that identifies resources in your environment that are reachable from the public internet. Network Scanning probes your resources from the internet to detect actual reachability, complementing the existing network reachability findings in Security Hub that identify configurations that could make a resource reachable. It discovers public IP addresses, virtual machines, and load balancers across your AWS and Azure environments, identifies reachable ports, and determines what services are running behind them. Each reachable port generates a Security Hub finding with evidence of the port and service discovered. Security Hub Exposures then automatically correlates these findings with other findings and resource configurations to determine broader risk. Existing customers can enable Network Scanning in individual accounts and Regions, or across an organization through a configuration policy. For new customers, Network Scanning is on by default. It is included with Security Hub Essentials at no additional cost.
Security Hub also extends unified security management to Microsoft Azure – Security Hub now monitors Microsoft Azure resources, providing unified posture management, vulnerability management, and security response across both clouds. It automatically discovers Azure VMs, container images, Function Apps, and identities, and evaluates them for misconfigurations, internet exposure, and software vulnerabilities. AWS and Azure findings appear in the same prioritized view with the same formats and automation workflows.
Amazon SageMaker Studio integrates with Hugging Face for one-click model deployment and customization – You can now go from discovering a model on Hugging Face to working with it in SageMaker Studio in a single click. Select any supported model on Hugging Face and choose “Customize on SageMaker AI” or “Deploy on SageMaker AI” to land directly on the corresponding workflow page with the model pre-loaded. New customers receive a Studio environment created in seconds with pre-configured permissions for serverless model customization (including fine-tuning with custom reward functions for reinforcement learning), model evaluation, and deployment to SageMaker or Bedrock endpoints. Verified customers receive default GPU access to G5, G6, and G4dn instances without requesting quota increases, and quota utilization is visible directly inside the Studio environment.
Amazon EKS Auto Mode and Amazon ECS Managed Instances reduce GPU management fees by up to 60% – Beginning July 1, 2026, EKS Auto Mode and ECS Managed Instances reduce management fees for accelerated instance types: G-series fees are down 35%, and P-series and AWS Trainium fees are down 60%. The reductions apply automatically to existing clusters and require no action from customers. Both services include capabilities built for accelerated workloads. EKS Auto Mode provides automatic parallel image pulling on GPU instances with local NVMe storage and accelerator-aware node repair. ECS Managed Instances provides GPU metrics through Amazon CloudWatch Container Insights and automatic health monitoring for GPU hardware failures.
Amazon Aurora DSQL change data capture (CDC) is now generally available – Aurora DSQL CDC streams the results of insert, update, and delete operations as change events to Amazon Kinesis Data Streams. You can use it to synchronize data across microservices, trigger Lambda functions, or deliver changes to S3, Redshift, and OpenSearch Service through Amazon Data Firehose. CDC streaming is designed to have zero impact on database workload performance and requires no infrastructure to manage.
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
Other AWS news Here are some additional posts you may find useful:
Building secure AI agents at scale: Introducing Loom for AWS – Loom is an open-source enterprise platform for building agents with AWS Strands Agents and deploying them on Amazon Bedrock AgentCore Runtime. It provides a unified management UI and backend API with identity provider integration, scope-based authorization, multi-persona navigation, and full lifecycle management for agents, memory, MCP servers, and agent-to-agent integrations. Loom enforces automated resource tagging for cost attribution, implements RBAC and ABAC for multi-tenant security, uses paved-path blueprints for agent deployments, manages identity propagation through delegated actor chains, integrates with AWS Agent Registry for discovery and governance, and supports human-in-the-loop review before sensitive actions. The project is available in AWS Labs on GitHub.
Introducing Claude apps gateway for AWS – The Claude apps gateway is a self-hosted control plane that gives organizations centralized control over access, cost, and policy for Claude Code and Claude Desktop. It connects to any OIDC-compliant identity provider, enforces managed settings on every request, routes inference to Amazon Bedrock or Claude Platform on AWS, and supports per-user and per-group spend caps. The gateway runs as a stateless container in your private network, backed by a PostgreSQL database for short-lived sign-in state. No long-lived secrets are stored on developer machines. Deploy it through Amazon Bedrock to keep data within the AWS security boundary, or through Claude Platform on AWS for the native Claude platform experience.
Introducing OAuth support for AWS MCP Server – You can now connect agents to the AWS MCP Server using browser-based OAuth with the same credentials you use for the AWS Console or CLI. The new sign-in path supports IAM federation, AWS IAM Identity Center, and root or IAM users. AWS Sign-In issues short-lived access tokens and refresh tokens, with automatic token management so developers stay authenticated across restarts. For headless use cases, a non-interactive flow lets applications with existing AWS credentials obtain OAuth access tokens through the create-oauth2-token-with-iam API. New governance controls include OAuth-specific IAM condition keys, token introspection and revocation, dynamic client registration, and CloudTrail audit elements.
For a full list of AWS blog posts, be sure to keep an eye on the AWS Blogs page.
Upcoming AWS events Check your calendar and sign up for upcoming AWS events:
AWS Summits – Free in-person events for builders and innovators to learn, think big, and make new connections. Coming up: Taipei (July 15), Bogotá (July 30), Jakarta (August 6), Ciudad de México (August 12), Johannesburg (August 19), and Zurich (September 2).
Visit the AWS Builder Center to meet other builders, contribute solutions, and find resources that help you keep building.
Wishing everyone a restful and enjoyable summer. Whether you’re building, learning, or recharging, I hope you find time for all three. I’ll be heading to Scandinavia for a few weeks to trade the heat for some cooler weather and longer evenings. Come back next week for more news!
Today’s data-driven tools can make many aspects of our personal lives less time-consuming, because they present us with options and even make decisions for us. By relying on predictive text features, we write messages more quickly and outsource our word choices. By using music and film recommendations, we outsource our personal taste. And by using AI chatbots that produce confident answers to every single one of our questions, we outsource our thinking.
Of course, I use and enjoy all of these products. But because I grew up before data-driven tools existed, I also know the accidental delights of exploring a city without a smartphone map, the joy of thoughtfully choosing a gift for a friend, and the satisfaction of comparing insurance quotes and understanding their details. These non-AI-assisted acts exercise my critical thinking skills — something that is harder to do in a world where AI products promise so much convenience.
Critical thinking is even more vital now in the age of AI. The brand-new issue of Hello World — and our new podcast mini series — offers research, advice, and practical resources for teaching young people, and ourselves, to think critically.
In issue 30 we share articles from educators who have already been thinking deeply about the role of critical thinking in the age of AI. They discuss a range of questions such as: What do educators bring to the table when teaching with digital technologies? Why AI professional learning should build teachers’ critical thinking, not just their confidence in using tools Whose knowledge is shaping AI?
Our feature articles also include: • Managing cognitive load for deeper thinking • AI systems in assessment • Promoting human decision-making
From the team at the Computer Science Teachers Association (CSTA) in the USA we have an article about their newly rewritten CSTA K–12 Standards, a research-backed framework designed to prepare students for a future that seems to be arriving very fast on some days. As their article says:
“AI can generate answers instantly, but understanding and evaluating answers still requires human judgement. In a world moving at supersonic speed, CS education needs to find a new balance. Students must learn to think critically so they can direct AI rather than being directed by it.” – Amanda O’Mara, Smita Kolhatkar, and Tiffany Jones in Hello World issue 30
Download Hello World issue 30 for free
Developing critical thinking skills is important for young people, regardless of the discipline you teach. In the age of AI, computing education is uniquely situated to cultivate this mindset, encouraging students to engage more thoughtfully with the AI tools they use daily.
Also in issue 30: • Flatgames • Predictive classroom systems • A physics meets technology project
Let us know which articles you found most helpful for your teaching or which resources you tried out by sending us a message or tagging us on social media.
Thank you to Oracle for sponsoring this issue of Hello World.
Cisco has some unusual challenges when it comes to deploying security patches
across the company’s many devices running custom kernels. John Fastabend spoke
about his work preventing exploits with BPF at the 2026
Linux Storage,
Filesystem, Memory-Management, and BPF Summit.
The technique could substantially reduce the time necessary to respond to kernel
vulnerabilities, but it will not be fully effective unless more hooks are added
to the kernel.
Debian has announced the final normal update for Debian 12 (“bookworm”). Long-term-support updates will continue until 2028. As may be expected from a stable version, the update is mostly limited to security fixes. Still, it may be time for Debian users to look into upgrading to a more recent version. Conveniently, Debian 13 (“trixie”) also received an update this weekend, with many of the same security fixes.
Healthcare organizations seeking HITRUST i1 certification increasingly rely on Amazon Web Services (AWS) as their cloud foundation. The HITRUST i1 assessment covers 182 curated controls at the Implemented level and is the most widely required HITRUST certification tier in healthcare vendor contracts and Business Associate Agreements required by health plans, hospital systems, and business associates as a condition of working with them.
This guide is designed to close the gap between understanding what HITRUST i1 requires and knowing how to implement it on AWS. It walks cloud architects, security engineers, compliance leads, and assessment preparation teams through the full lifecycle of an i1 engagement from defining the assessment boundary to implementing controls across each technical domain.
What the guide covers
The guide addresses 11 HITRUST i1 technical control domains, with supporting AWS implementation components relative to these domains. The domains include access control, endpoint protection, configuration management, vulnerability management, network protection, transmission protection, incident management, data protection and privacy, audit logging and monitoring, password management, and business continuity and disaster recovery.
The guidance is grounded in a fictional but realistic connected healthcare platform deployed on AWS Landing Zone Accelerator. The scenario is used to make abstract HITRUST concepts concrete, not to suggest that the same architecture or control choices apply universally. HITRUST i1 scoping is inherently organization-specific. The assessment boundary, applicable controls, and evidence requirements are determined by each organization’s system scope and delivered through the HITRUST MyCSF portal. Readers should treat the guidance as a starting point and work with a HITRUST Authorized External Assessor to validate what applies to their specific environment. This guide doesn’t constitute a compliance certification advisory.
AWS HITRUST assurance documentation and the Customer Responsibility Matrix are available through AWS Artifact. For assessment readiness support, visit AWS Security Assurance Services.
If you have feedback about this post, submit comments in the Comments section below.
Bot mitigation is an adversarial game: attackers adapt, defenders respond, and the cycle continues. At Cloudflare, we stay ahead by combining visibility across our global network with signals from the client-side environment. At the network level, we analyze over 1 trillion requests per day to understand reputation, patterns, and anomalies across more than 20% of the web. On the client side, we’ve pushed detection deeper with Cloudflare Turnstile, which has evolved from a CAPTCHA replacement to a risk-based managed challenge that adapts the amount of friction needed to verify the user is authentic.
Today, Turnstile runs nearly 3 billion times per day on some of the most sensitive endpoints on the Internet, helping verify users at key moments like login, signup, and checkout. This improves protection on the most important areas of customer applications, but still leaves limited visibility into the rest of the application — how humans and bots actually interact across the full user journey.
This is the visibility gap we’re closing today with our launch of Precursor.
Introducing Precursor
Precursor is a client-side, session-based verification system, built with privacy in mind, that uses dynamically injected JavaScript to continuously collect behavioral signals as visitors interact with your application. These signals are processed and incorporated into Cloudflare’s bot protection in real time, allowing us to continuously distinguish human traffic from automated or agentic traffic.
This extends the client-side detections offered by a Challenge to your entire web application. Precursor is an optional complement to Turnstile — both are features of our Enterprise Bot Management.
This user-journey-based detection is powerful because modern automation is increasingly capable of appearing legitimate in short bursts. Bots can execute JavaScript, use real browser environments, and pass individual CAPTCHAs without raising suspicion. What remains difficult to replicate is consistent human behavior over time.
Precursor is built to capture that layer of interaction, turning behavior itself into a reliable signal for detecting fraud and abuse. By evaluating behavior across an entire session, Precursor adds significantly more signal to each decision. This improves detection precision, making it easier to distinguish real users from automation without relying on aggressive Challenges. For legitimate users, Precursor means fewer unnecessary interruptions. For bot developers, it raises the cost of operating automation by requiring them to simulate a full session. This is significantly harder to build, more expensive to maintain, and far less reliable to operate at scale.
To err is human
When a bot developer tries to make a mouse movement look human, they usually add Gaussian noise or uniform random delays. But human movement isn’t just “noisy,” it is also constrained by physics:
Wrist pivot: A human mouse movement is often an arc, limited by the range of the wrist and the rotation of the forearm.
Cognitive load: There is a measurable delay between a human seeing a checkbox and clicking it.
Hand tremor: Even the steadiest human hand oscillates at a physiological tremor frequency.
Bots, by contrast, often behave in ways that give them away. They move in linear interpolations or mathematically ideal Bézier curves. They click with a precision that humans could never replicate. And even when they do manage to simulate human error, there is a rhythm to human movements that can only be seen by examining an entire session.
Mouse movement is just one example of the signals Precursor evaluates, but it illustrates the difference clearly. Below is an example of a mouse automation library interacting with a site. You can see how the mouse moves in perfectly straight lines, always returns to an origin, and reacts with the same velocity.
Now, contrast that with a human navigating the same site: you see irregular paths, small corrections and overshoots, and variations in speed, timing, and direction.
Individually, these interactions might look plausible. But over the course of a session, these patterns diverge in ways that are difficult to fake. Precursor is designed to capture and evaluate these behavioral signatures as they develop over a visitor’s interaction with an application.
How Precursor works
To evaluate behavior over time, Precursor continuously collects interaction data on the client and builds a session-level view of activity for that site.
1. Injection and collection layer
When Precursor is enabled on your application, Cloudflare automatically injects a lightweight script into HTML responses from your site as they pass through our network, with no additional configuration, network connections, or third-party embedding required. The injected Precursor bundle is compact, obfuscated, and assembled dynamically for each response. The bundle is designed to not interfere with any additional page logic of the hosted web application.
The script attaches lightweight event listeners to capture interaction signals such as pointer movement, keyboard activity, focus changes, and visibility. These events are serialized into a compact format and buffered in memory. At regular intervals, the buffered data is sent back to the evaluation layer for analysis.
2. Evaluation layer
On the edge server, incoming Precursor payloads are deserialized into behavioral inputs. A dispatcher runs a roster of evaluators on the input data. Each evaluator reads the Precursor streams it cares about and can raise signals into the shared detection registry.
Evaluators are designed to cross-reference data. For example, they confirm that pointer activity correlates with page visibility duration, or that keyboard events only fire when a text field is focused. This stream of information is then consolidated into individual signals that are used for weighting detections.
3. Session integration
Precursor data is session-scoped, meaning it accumulates throughout a session. Session scoping is important because it means a bot cannot reset its behavioral signature by refreshing the page or starting over with a new challenge. The system also feeds session metadata into downstream detection layers for additional shadow-mode heuristics and session analysis, predicted vs. actual completion, and session delinquency heuristics. These edge-side observations are logged for detection improvement purposes and to adjust the bot score of a session.
4. Privacy by design
Precursor was designed to collect signals that help to distinguish human patterns from automated and abusive patterns.
The event listeners capture the minimum information needed to be a useful signal for detecting automation and abuse. For example, keyboard activity is captured as timing and rhythm, not as the actual keys pressed. In addition, behavioral signals are evaluated as aggregate patterns rather than individual actions and are consumed internally by Cloudflare’s bot detection systems; they are not exposed to customer dashboards or tied to user accounts, login identities, or persistent profiles.
Taken together, this allows Precursor to maintain a continuously evolving evaluation of behavior, maximizing precision while minimizing the friction on good users.
Per-session analytics
To support this new layer of detection, we are introducing session-based views in Security Analytics. These dashboards shift the perspective from individual requests to full visitor journeys. You can now answer questions like:
What does a typical session look like on my site?
Where do sessions diverge from expected behavior?
Which sessions show signs of automation over time?
Use Security Analytics to explore session-based views for your bot management traffic.
These analytics now capture information that per-request analytics can’t — especially the behavior that occurs between requests. Precursor feeds directly into existing systems like bot score, challenge decisions, and security rules, so you benefit from this added context immediately.
What’s next
Precursor is the foundation for extending bot detection across the entire application. We are continuing to expand the range and depth of behavioral signals for security, how session-level insights influence our bot management protections, and new ways to visualize and act on session data. As bots evolve, detection needs to move beyond isolated checkpoints and into the full flow of user activity.
Get started
Precursor is rolling out now and can be enabled directly from your Cloudflare dashboard. Precursor will be free to use until our GA release later this year. Getting started is simple: turn Precursor on for your zone and choose how strictly you want to verify sessions. You can run it in a low-friction mode to observe behavior in the background, or require a fully verified session by enforcing Challenges if a session doesn’t already exist.
Once enabled, Precursor begins enhancing your existing bot defenses immediately, with no changes required to your application. If you’re already using Bot Management or Turnstile, Precursor extends those protections beyond Challenges and into the rest of the session. Enable Precursor to extend detection across the full user session, including the activity between moments you already protect.
This essay was written with Nathan E. Sanders, and originally appeared in The Guardian.
Opposition to AI data centers has emerged as a primary theme in US politics, one that—surprisingly—doesn’t fallalong party lines. We applaud people coming together for constructive debate on any issue, and agree that communities need to evaluate whether any economic benefits these data centers bring is worth their costs. Still, we worry that a focus on data centers obscures the larger impacts of AI on people’s lives: the concentration of power of AI companies, and their widespread political and financial influence.
Local data center opposition is grounded in legitimate concerns about misallocation of land resources when housing is at a premium, pressures on already higher energy prices, and localized environmental impact. Unlike other resource-consuming and polluting industrial facilities, data centers produce very few jobs. The fact that US opposition to data centers seems to be most fierce among lower-income communities reflects righteous indignation with an inequitable bargain, where tech companies and developers profit from exploiting local resources but offer little in return. On a global scale, their carbon footprint could grow unsustainably if usage accelerates. And all this is in aid of a technology that many fear will propagate misinformation, take their jobs, or even cause existential risks for humanity.
For some, data center opposition may feel like the only tangible mechanism for registering their concern, disapproval, or even anger about AI. The problem is that this may be exactly what the AI companies are banking on. They can overcome the protest when it matters to them, and live with a significant fraction of proposals being defeated. More importantly, focusing political opponents on the data center issue obscures the bigger prize they’re after.
While there is a staggering three-quarters of a trillion dollars being spent on data center infrastructure by US companies this year alone, this investment should be taken in perspective. The market for enterprise software, for example, is about twice this size. And it’s small compared with what these companies actually want.
AI companies have their eyes set on capturing all the value created by entire industries. The technology has arguably already conquered customer service and consumer sales. But on the horizon are bigger targets, such as enterprise software development, creative design, management and even legal services. In AI companies and their allies’ vision of the future, AI replaces teachers and doctors. The companies would rather spend time fighting resistance to how fast they are building computing infrastructure than dealing with issues of how their products should be used in those fields, or how those fields should be protected from their products.
And while data center opposition campaigns have been successful in building widespread appeal, their effectiveness in the US is mixed. They seem to be most successful when organizing against speculative, early-stage data center proposals that have a relatively low likelihood to ever see fruition. Meanwhile, advanced-stage, well-capitalized data center projects have proven to have the resources to overcome local opposition. An OpenAI- and Oracle-backed facility in Saline township, Michigan, is breaking ground on construction even after local officials voted to reject it. The developers sued the town of 3,000 and forced a settlement that involved their project going forward. Meanwhile, the Trump administration, a vigorous ally of corporate AI, has signaled its willingness to advance AI infrastructure development by overriding state objections and even using federal lands.
Also consider that rampant data center development may be a momentary spike rather than a longstanding concern. Demand for the centralized computing that data centers provide may well decline over time. The leading Chinese labs, such as Z.ai, are innovating in technical mechanisms to make frontier-class models smaller and cheaper to run. AI power users have become adept at miniaturizing open weight models, ones published free for anyone to download and use, to run locally on their own computers. Apple and Googleboth support infrastructure stacks for running AI models directly on mobile phones. It could be that the current mania for data centers will look like the fiber optic cable bubble from the early 2000s, as demand shifts to smaller models and AI usage on people’s own devices.
For those concerned primarily with affordability and environmental protection, singling out data center construction is misplaced. Energy rates and inflation today seem to be most visibly affected by the US-Iran war. The US is disinvesting in long-term energy security by ceding the renewable energy industry to China and actively cancelling climate commitments. Consider that 10% of global carbon emissions stem from heating buildings, which dwarfs energy use by AI and could be cut fivefold by using heat pumps powered by renewable energy. With respect to housing affordability, federal housing subsidies have changed little over three decades, in inflation-adjusted terms, even as housing costs have spiked and homeowners have enjoyed robust tax incentives.
As for AI itself, the concentration of power and wealth in these tech companies is the greatest existential risk facing society today. This means we must limit corporate power, especially corporations’ ability to exploit the public and manipulate our political system.
Opposing data centers should be just a starting point. We can advocate for states to regulate AI, to reject irresponsible uses of the technology, and shape corporate behavior. We can fight for AI computation to be taxed, so that the public can capture some of the profit of AI use while also forcing AI companies to internalize more of the energy and environmental consequences associated with its use. And we all can join the global movement for Public AI, an alternative ecosystem for AI that is developed under public control with an incentive structure to create public benefit rather than private profit.
The US midterm elections present ample opportunity for those seeking to control the AI political agenda. In the recent New York congressional Democratic primary, PACs linked to the dueling AI companies Anthropic and OpenAI spent millions of dollars lobbying for or against “AI safety“, the idea that we must urgently monitor and prevent people from using AI to cause catastrophic harms. We’re already seeing a similar dynamic play out in races in Massachusetts and other states.
Why would Anthropic and OpenAI—bitter industry rivals but fundamentally on the same side politically—support opposing viewpoints? Because they both ultimately profit from the mystique: the idea that their products are so powerful that controlling those products is the world’s most important challenge. Here’s the typical read on the dynamic. To one side (backed by OpenAI affiliates), “safety” comes from the appearance of US industry dominating AI innovation, under the slow-moving control of federal lawmakers (and without pesky state regulators in the way). To the other side (backed by Anthropic), “safety” means a heavier regulatory framework that plays to Anthropic’s posturing as the ethics- and compliance-focused AI vendor. In both cases, it’s more marketing than principled concern about safety.
Political organizers should call out and reject the AI companies’ framing of the debate, and reorient campaign agendas around populist resistance to corporate concentration of wealth and power. When AI companies pump millions into legislative races, the result should not be hyperbolic discussion of AI superintelligence. And when a plot of land in a small town is pitched as a data center site, the debate should be about more than the local costs and benefits. It should include out-of-control money in politics, and Citizens United-proof solutions to limit corporate influence like public financing and state regulation.
We all have a vested interest in what’s on the policy agenda, and what the outcomes are. Today, the greatest risk AI poses to society is the exacerbation of inequality and the concentration of wealth. The real problem is trillion-dollar AI companies and their trillionaire oligarchs cozying up to political power in Washington and governments worldwide, and using their money to enact their agenda over the popular will of the people. This is the issue we’d like to see put front and center, and it requires solutions much more extensive than slowing data center development.
Частната телевизия е като плод-зеленчук: „Отиваш сутринта, отваряш, хората купуват, ако са ти хубави продуктите; ако са лоши, не купуват.“ Така разказа бизнеса си един от собствениците на bTV – Красимир Гергов, в едно от малкото си интервюта по повод десетата годишнина на първата частна национална телевизия у нас. Петнайсет години по-късно телевизията е превърната в кебапчийница – поне ако се съди по меметата, украсили последния публичен скандал за цензура и произвол в една от все още най-големите медийни институции в държавата.
Всичко започва, след като 19-годишният Мартин Атанасов (автор на „Черна писта“ и „Диагноза България“), поканен за гост в предаването „Лице в лице“, публикува скрийншот от вътрешна комуникация в нюзрума на bTV, от който става ясно, че участието му е спряно с разпореждане отгоре. Той трябваше да сложи на тезгяха темата за течовете в здравеопазването, за които плащаме всички ние. Но тя се оказа „неважна“ – свалена еднолично с кратък текст от директора на отдел „Новини, актуални предавания и спорт“ Асен Иванов. Заради някаква си чаша.
Този с чашата ли .. никога Да ходи в Извън ефир .. може да го скрийшотнете и сложите в Фейса Този няма да стъпи в ефир на бтв, докато зависи от мен
разпорежда началството с високомерната безнаказаност на човек, който знае, че се отчита другаде, а не пред обществената санкция на социалните мрежи. Можем само да предполагаме, че на някого от участниците в разговора също му е преляла чашата и затова този вътрешен чат получи публичност. За съжаление, това е максималната степен журналистически бунт и несъгласие, които може да очакваме в момента.
Продуцентката, поканила госта, го връща, лъжейки вместо началника си и прикривайки предварителната цензура, на която тя, екипът и събеседникът са подложени. Ръководството на медията също застава зад документирания властови произвол с клишето „редакционно решение“.
Че това не е легитимно редакционно решение и защо една телевизия не може да си прави каквото си иска в новините дори когато е частна, ще стане дума след малко.
Преди това – какво разгневи Асена на „bTV Новините“? Да го наричам „директор новини“, макар и фактически вярно, ми се струва обидно за всеки останал професионалист в екипа на медията, както и за самата функция, която помни по-добри времена, лица и имена.
Кой е Асен Иванов?
Официалната му биография го представя като дългогодишен журналист на bTV – криминално-съдебен репортер, редактор и така до главен редактор. Завършил е право в Югозападния университет в Благоевград, а след това и национална сигурност във Военната академия. От официалната му биография обаче трайно е изпаднал един интересен епизод: между 2012 и 2017 г. Иванов работи в ТВ7 – финансираната от КТБ телевизия, превърната в политически инструмент на Цветан Василев, Делян Пеевски и Николай Бареков. Там се издига до изпълнителен продуцент. Но през 2017 г. се връща в bTV, поканен от Венелин Петков, въпреки вече ясното му осветяване като част от политически инженеринг в журналистиката.
История с чаша, но не за чаша
Историята с чашата вече е клише. Когато в края на миналата година Мария Цънцарова беше отстранена от ефира на bTV, официалното съобщение на медията посочи като повод именно някаква чаша, с която тя си позволила да се яви в ефир. Обяснението беше толкова несъстоятелно, че на момента се превърна във фолклор, а чашата с надпис „Време за истинска промяна“ – в символ на протест в подкрепа на свободната журналистика.
Горе-долу по това време с тази именно чаша се яви Мартин Атанасов в студиото на bTV при седналия в опразненото столче на Мария Цънцарова неин колега Росен Цветков. Подари му я и го призова да пази достойнството на професията.
Този жест явно е засегнал директора на новините достатъчно, за да го спомене в официалната си позиция от миналата седмица. В нея той признава, че лично е свалил гост от ефир, през главата на редакционния екип, заради „целенасочена провокация и неуважение към наш водещ“. И добавя:
Когато един гост използва ефира за предварително планирани демонстративни действия, това неизбежно поставя въпроси за доверието между него и редакцията, както и за целта на участието.
И тук вече личат дефицитите и на самия аргумент, и на човека, който го артикулира. Първо, това, че гостът идва с предварително подготвено обществено послание, не е доказателство за недобросъвестност. Напротив – подготовката на госта е знак за сериозно отношение както към медията, така и към публиката. Освен ако самото послание в защита на свободната журналистика не се приема като обида към екипа, но това вече казва повече за обидените, отколкото за намеренията на госта.
Отделно, медия, която е извела в свое мото „силата да бъдеш информиран“, не може и не трябва да очаква от своите събеседници само позиции, които са ласкателни за самата нея. Години наред същата тази телевизия твърдеше, че търси всички гледни точки. Включително на един критичен към медията гост, който впрочем не беше единствен в онези дни. Не е приятно преживяване, но със сигурност не е легитимен повод за задраскване на събеседници. Защото това не са корпоративни отношения между партньори.
Телевизията е партньор на зрителя. Него обслужва и заради него трябва да е готова да изслуша дори онези, които не харесва.
Няма такова доверие – между гости и редакция. Няма тест за лоялност, за да те показват по телевизора. Както впрочем няма и абсолютна лоялност на журналистите към собствениците и главните редактори. Това не е клуб по интереси, затворена Facebook група или мафиотска структура, в която да стъпва кракът само на проверени и доверени хора.
В едно свое интервю началникът на „bTV Новините“ споделяше с гордост, че телевизията му се гледа от хората с власт. И явно за него е достатъчно. Но не за това доверие работи шефът на новините. А за доверието между медията и публиката. То е валутата в този бизнес. Нещо като сертификат за качество или печат от ХЕИ, предполагам, за една кебапчийница.
Оттам и основната задача на шефа на новините: да избира и развива журналисти и формати, които се ползват с обществено доверие, и да им осигурява гръб, за да го поддържат. Толкова. Плюс щипка рейтинг. Това работят шефовете на новини в търговските телевизии. На теория.
На практика всички виждаме, че явно има абонамент с проверени гости за ефира не само на bTV. От сутрин до вечер гледаме едни и същи лица, които често говорят с чужди гласове. Те и затова са канени – пращани са от пресцентрове и политически пиари да изговарят теза от името на една или друга скрита сила зад безотговорността на „независим“ анализатор.
Това са проверените хора в медиите, които не застрашават доверието. Могат да идват с теми от частен интерес на един или двама души в държавата и да говорят „за хората“. И никакви обиди на никакви водещи не могат да спрат триумфа на тези говорители в ефира на bTV, а и на останалите големи телевизии. Така например когато лидерът на „Възраждане“ нападна с обиди Мария Цънцарова в собственото ѝ студио през 2024-та, медията мисли два дни и написа някакво съобщение в подкрепа, но клетва, че кракът му няма да стъпи повече, нямаше.
bTV не може да си кани когото си иска дори когато един Асен е шеф на новините
Телевизия като bTV, дори гледана като плод-зеленчук или скара-бира, работи с ограничен обществен ресурс – ефирната честота, предоставена ѝ с лиценз и срещу конкретни задължения към публиката. Това не я прави държавна, но я прави нещо повече от обикновена частна фирма.
лицензът не е нотариален акт за собственост върху ефира. Той е обществен договор. Срещу правото да използваш честоти и да печелиш милиони от вниманието на милиони хора приемаш задължението да им даваш качествена информация в техен интерес, добита чрез равен достъп и плурализъм на гледните точки, отстоявани през редакционна независимост.
Така bTV не може като продавачката в кварталната бакалия, разположена в собствен гараж, просто един ден да реши, че няма да обслужва хора с руса коса, примерно. Всъщност и в бакалията не може така, защото би било дискриминация. И понеже, за щастие, не живеем на ориенталски пазар, където „всеки сам си преценя“, а във все-още-уж-законова държава, има норми и регулатори, които би трябвало да следят да не се самозабравят онези, които вярват, че няма кой да ги накаже.
Любопитното е, че в онова интервю от 2010-та Красимир Гергов, изглежда, го разбира това:
Не може, както в другите фирми, идват и казват на собственика: „Направи така.“ Тук има свобода на словото.
На кого говори и дали това не е по-скоро публично оправдание за случващото се в ефира по онова време, можем само да гадаем. Но поне теорията беше вярна. Или поне се полагаше усилие да изглежда така, сякаш телевизията не е бащиния. Дори и ако това е било само „за пред хората“.
Законът за радиото и телевизията забранява политическата и икономическата намеса и цензурата в дейността на медиите (чл. 5). В същия закон е записано, че журналистът може да откаже възложена задача, когато тя противоречи на закона, на личните му убеждения или на професионалната му съвест (чл. 11). И макар българската рамка да оставя достатъчно удобни вратички за натиск и интерпретация, смисълът е ясен:
журналистът не е войник в казармата на директора.
От август 2025 г. това вече не е само пожелание от учебник по журналистика. Европейският акт за свободата на медиите е факт и трябва да се прилага пряко и в България, нищо че не сме разбрали това да се е случило. Той изисква медиите да предприемат реални мерки за независимостта на редакционните решения и да разкриват конфликтите на интереси, които могат да влияят върху тях. Европейският законодател специално посочва риска акционери и собственици да бъркат границата между стопанската си свобода и редакционната свобода.
С други думи:
да, директорът на новините има право да ръководи редакцията. Да определя стандарти, да приоритизира ресурси, да изисква проверка, да връща недостоверни материали, да носи отговорност за програмата.
И не, няма право да превръща личната или корпоративната си обида в редакционна политика, да наказва събеседник за публична позиция или да отменя вече взето професионално решение на екипа само защото „от него зависи“.
Едноличното „никога!“ не е редакционна корекция, а намеса. И понеже е записано черно на бяло, този път няма нужда да гадаем дали е имало натиск, дали някой се е обадил и дали всички просто са се разбрали по телепатия.
Редакционният екип, разбира се, също има право да каже „не“. Това, че един Асен е поискал да прогони събеседник, не превръща желанието му в задължителен мандат. В най-лошия случай могат да те уволнят. Което съвсем не е малко, особено в държава с миниатюрен медиен пазар и с години систематично прочиствана професия.
Защо няма съпротива отвътре?
Разбира се, лесно е отстрани да питаме защо продуцентката не е отказала, защо е излъгала госта, защо никой не е станал и метнал чаша в ефир. Повече съпротива би била добър знак за състоянието на професията. Но след дългогодишна негативна селекция и регулярна санитарна сеч в медиите един журналист трудно може да се окаже по-силен от цялата система. Особено когато няма институционална защита, няма гилдийна солидарност, а обществената подкрепа приключва с възмутен пост във Facebook. Затова днес споделянето на един вътрешен скрийншот минава за бунт.
Оставете дебатите на журналистическите факултети, те добре се справят с тая работа. Регулаторът работи друго: да проверява спазва ли лицензираната медия закона и европейските изисквания за редакционна независимост и ако не – да налага санкции. Задачата на СЕМ е да предпази журналистите от натиск, включително когато той идва не от политик пред асансьора, а от собствения им началник. И ако законът не дава достатъчно силни инструменти, поне да го каже ясно и да изиска такива. Свикнали сме с бездействието на регулатора в подобни случаи и не очакваме нищо по същество, но това е част от проблема. И опитите да се прикрие с часове безсмислено говорене само го доразобличават.
Има ли кой да ги накаже?
Сигурно. Американската публика например направи показно при кризата около ABC и Джими Кимъл. След политическия натиск и временното сваляне на предаването реакцията не остана само в социалните мрежи. Абонати и инвеститори насочиха гнева си към Disney – корпорацията, която реално държи парите и взема решенията. Кимъл се върна в ефир шест дни по-късно и записа най-високия си рейтинг от години. Не защото корпорациите внезапно са развили съвест. А защото някой е превел възмущението на хората на езика на парите.
Дори Джеф Безос, когато реши да наложи волята си над редакционната позиция на собствения си Washington Post и спря подготвената подкрепа за Камала Харис преди изборите през 2024 г., не успя да представи намесата като нормално редакционно решение без цена. Последваха оставки, открит бунт в редакцията и над 200 000 прекратени абонамента.
В нашия случай заформилият се опит за бойкот, струва ми се, не трябва да е насочен само към bTV – компрометирания медиен бранд в портфолиото на корпорацията майка. Призивите да не се ходи в студиата, обзаведени по правилата на асеновци, са симпатични, макар и доста лицемерни, а в най-добрия случай – тежко закъснели.
Ако изобщо ще се упражнява потребителски натиск, той би имал смисъл единствено ако е насочен към другите търговски активи на същата корпоративна група в България, като телекоми например. Там е касата.
Телевизията може да преглътне няколко отказани гостувания и ядосани поста в социалните мрежи, но златните яйца днес се снасят не в бизнеса с ефирните честоти, а по телекомуникационната вертикала. Там бойкотът може да се преведе на езика на бизнеса.
Но засега у нас сме по-силни в чашите, статусите и моралното превъзходство.
И тук влиза неудобният въпрос как въобще един Асен стига до позицията, от която може да разпорежда „този никога“ на цял редакционен екип. Вътрешният чат не е началото на историята, а моментът, в който един Асен излиза от гардероба. Де да беше само той…
Асеновците не падат от небето и не се самоназначават.
Те са ГМО производство на българската журналистика в големите медии. В конкретния случай въпрос има и към Венелин Петков, при чието ръководство Иванов се връща в bTV след ТВ7 и постепенно стига до управленски позиции.
По какви професионални критерии е върнат? С какви гаранции, че школата на ТВ7 е останала зад гърба му, а не е дошла с него в нюзрума?
Няма смисъл да се посочва един-единствен виновник. Асен е възможен, защото зад него има цяла система от назначения, премълчавания, компромиси и професионални амнистии. Система, която приоритизира лоялността пред моженето, гъвкавостта пред стандартите, съобразяването пред отстояването.
Ако се върнем към онова интервю с Красимир Гергов и плод-зеленчука и сравним казаното от него с изявите на днешните телевизионни господари, ще се наложи един очевиден извод: политически игри с телевизията винаги е имало, но нивото определено пада.
От онова интервю смятам, че несправедливо се запомни само цитатът със зарзавата, а от днешна гледна точка там има и доста по-ценни свидетелства:
Българските медии вече са доста големи деца, за да може някой да ги бие по дупето и да слушат каквото някой им каже отгоре. Така че ние винаги ще намерим начин, ако някой ни притиска, да излезем от ситуацията. Не смятам, че политиците са толкова глупави да налагат ежедневен контрол върху медиите, защото това ще бъде краят им.
Наивно, нали. През 2010 г. все още звучеше възможно.
Една друга сбъднала се прогноза от днешна гледна точка ми се струва много подценена. Интервюто е дадено малко преди медийният октопод на Пеевски с подкрепата на Цветан Василев да насочи пипалата си от вестниците към телевизиите.
След цифровизацията, казва Гергов тогава, ще се появят „много влиятелни и не толкова влиятелни“ хора, които ще се опитат да правят медия, използвана за влияние. „Това вече е страшното за обществото.“
И още:
Ако вие сте честни към това, което правите, и давате добър продукт и всички гледни точки, ще бъдете номер едно. Ако бъдете тенденциозни и изпълнявате всички поръчки на собственика, който, да кажем, се занимава с нещо си – приватизатор някакъв, да кажем, занимава се с кокошки – и вие по цял ден давате кокошки или хора, свързани с този бизнес, няма кой да гледа тези телевизии.
Наистина няма кой да ги гледа. Но вече няма и особено значение. Когато кокошарникът пише рейтингите или телевизията е станала витрина на други бизнеси, или сделката вече е кон за кокошка, за да продължим със селскостопанската метафора.
А всъщност телевизията не е нито зарзаватчийница – по чисто комерсиалния модел, нито кебапчийница – по модела „който плаща, той поръчва музиката“. Тя е пазар. Пазар на идеи (marketplace of ideas), ако използваме класическата либерална представа, развита най-ясно от Джон Стюарт Мил. Тържище, на което освен фактите свободно се конкурират различни интерпретации, аргументи и разкази за реалността. Така истината има най-голям шанс да победи – в свободен дебат и в състезание, дори и с лъжата.
Това, разбира се, не означава, че всяка идея е еднакво вярна или че всяка телевизия е длъжна да даде трибуна на всеки. Редакторите ежедневно правят професионален подбор. И това не се нарича цензура, когато критерият е журналистически: достоверност, обществен интерес, компетентност, плурализъм. В момента, в който достъпът до пазара на идеи започне да се определя не от професионални стандарти, а от лични сметки, симпатии или желание някой да бъде наказан, тогава идеята се чупи. Превръща се в затворен клуб, продължение на обръча от фирми. А обществото губи не защото е победила грешната идея, а защото състезанието е било нечестно.
Enterprise video surveillance is operating at an unprecedented scale as organizations across retail, banking, quick-service restaurants (QSR), convenience stores, and transportation networks generate petabytes of video data across thousands of distributed locations. As retention requirements grow and organizations seek to extract more operational insights from video, traditional on-premise storage models are becoming increasingly difficult and expensive to scale.
March Networks is a global provider of intelligent video surveillance and business intelligence solutions serving enterprises across banking, retail, quick-service restaurants, transportation, and other multi-site environments. With more than 25 years of experience in video technology, the company helps organizations transform video data into operational insights through cloud-based platforms, AI-powered analytics, and enterprise-scale video management.
Unlocking the power of video data
In this post, we show how March Networks built a scalable cloud architecture on Amazon Web Services (AWS) to support large-scale enterprise video storage and analytics. The solution uses Amazon Simple Storage Service (Amazon S3) and Amazon S3 Glacier to manage long-term video retention, while integrating with additional AWS services to support ingestion, lifecycle management, monitoring, and secure access. We also explore how this architecture enables advanced video analytics using technologies such as Amazon S3 Vectors and Amazon Bedrock, helping organizations store petabyte-scale video data more cost-effectively while accelerating investigations and operational insights.
The challenge: Managing enterprise video at scale
Historically, enterprise video has been stored on local network video recorders (NVRs) and on-premise servers deployed at each site. Although this model provides localized control, it creates fragmented storage environments that require frequent hardware expansion, ongoing maintenance, and inconsistent retention policies across locations. This also limits organizations’ ability to centrally access, analyze, and govern video data across their enterprise.
As organizations increase video retention periods for compliance, liability protection, and operational intelligence, infrastructure requirements grow rapidly. Adding local storage hardware across hundreds or thousands of sites increases operational complexity and introduces lifecycle management challenges.
The economic impact of cloud video storage
Cloud storage introduces a more flexible model by consolidating distributed video data into centralized, elastic storage infrastructure. Even partial migration (such as moving long-term retention or compliance archives to the cloud), can significantly reduce infrastructure overhead while enabling centralized data management and analytics.
The financial impact of this shift can be substantial. For example, one retail organization evaluated the benefit of moving to a hybrid cloud storage model to extend video retention for a period of up to 5 years — a common retention window driven by compliance standards and laws — without adding new on-premise hardware. This customer operated more than 580 cameras, generating approximately 5,600 TB of archived video. The total storage required depends on factors such as video bitrate and quality, camera count, and backup duration. Their estimated cloud storage cost using a third-party cloud provider was approximately $347,000 per year, compared to roughly $1.7 million annually to store the same volume of video on-premise. For long-term cloud storage, data is not expired or deleted; customers are notified as their storage quota approaches capacity and can purchase additional storage as needed. By retaining recent footage locally while archiving older video to a third-party cloud provider, the organization significantly reduced storage costs while maintaining access to archived footage when needed.
Solution overview: March Networks cloud storage on AWS
March Networks Cloud Storage is a cloud-based video storage solution built on AWS. It is designed for distributed enterprise environments such as retail chains, financial institutions, convenience stores, and transportation systems that operate thousands of cameras across geographically dispersed locations.
The solution leverages Amazon S3 and Amazon S3 Glacier to provide scalable and durable storage for large volumes of video data while integrating AWS services that support secure ingestion, lifecycle management, monitoring, and access control. By combining AWS cloud infrastructure with March Networks’ video surveillance expertise, organizations can modernize video retention strategies while maintaining operational flexibility.
The platform supports multiple deployment models that allow organizations to adopt cloud storage at their own pace. Hybrid architectures allow recent footage to remain on-site for immediate access while older video is archived to the cloud. In other deployments, organizations can move a majority of video storage into AWS to reduce on-premise infrastructure and simplify long-term retention management.
Because the platform is built on AWS, storage capacity scales automatically as organizations add cameras, extend retention periods, or onboard new sites. This allows customers to grow video storage environments without hardware planning, or infrastructure expansion.
Architecture deep dive
The Cloud Storage architecture integrates on-premise video infrastructure with AWS services that manage ingestion, storage, monitoring, and secure access to video data.
At a high level, the architecture connects local video systems, including NVRs, cameras, and client applications, to AWS cloud services through secure network connections. March Networks securely ingests video data into AWS storage infrastructure, where customers can retain, monitor, and retrieve it based on their defined policies.
Figure 1: March Networks Architecture on AWS.
Video ingestion and storage
March Networks securely uploads video recorded on local NVRs to Amazon S3 buckets using encrypted transmission protocols. Amazon S3 provides highly durable object storage designed to store large volumes of data while enabling efficient retrieval and lifecycle management.
Once stored, organizations can retain video data for active investigations or operational review. Organizations configure lifecycle management policies that automatically move older footage to lower-cost storage tiers based on their access patterns.
Tiered storage with Amazon S3 and Amazon S3 Glacier
Video storage requirements vary depending on how frequently footage must be accessed. The platform uses multiple Amazon S3 tiers to align performance and cost with real-world video access patterns.
Amazon S3 Standard and Amazon S3 Standard-Infrequent Access (S3 Standard-IA) support video that must remain readily accessible for investigations, operational review, or analytics. For long-term retention, the platform uses Amazon S3 Glacier storage tiers to provide ultra-low-cost archival storage for footage that must be preserved but is rarely accessed.
Lifecycle policies automatically transition videos between tiers according to customer-defined retention policies. This allows organizations to store high-value recent video on high-performance storage while archiving older footage economically.
Supporting AWS services
Several AWS services support the reliability, scalability, and operational visibility of the platform:
Amazon Simple Queue Service (Amazon SQS) manages asynchronous messaging between system components, enabling reliable communication between ingestion, processing, and storage services.
Amazon Simple Email Service (Amazon SES) provides notification capabilities for operational alerts and system events.
Amazon CloudWatch monitors system performance, logs activity, and provides operational visibility into cloud infrastructure.
AWS Security Token Service (AWS STS) enables secure authentication and temporary credentials for system components accessing cloud resources.
For metadata management and caching, the platform uses PostgreSQL and Amazon ElastiCache for Redis to maintain high-performance access to video metadata and system state.
Together, these services enable March Networks to deliver a secure, scalable cloud architecture capable of supporting petabyte-scale video workloads across distributed environments.
Outcomes and benefits
By building its video storage architecture on AWS, March Networks enables organizations to modernize video infrastructure while reducing operational complexity and long-term storage costs. This includes:
Reduced storage costs
Tiered storage using Amazon S3 and Amazon S3 Glacier allows organizations to align storage costs with actual video access patterns. Frequently accessed footage remains readily available, while older video can be archived at significantly lower cost.
Elastic scalability
AWS infrastructure enables organizations to scale video storage across hundreds or thousands of locations without adding on-premise hardware. As organizations add cameras or extend retention periods, storage capacity expands automatically.
Centralized investigations and governance
Cloud-based video storage enables security and operations teams to investigate incidents across multiple sites using a centralized platform. Organizations can apply consistent retention policies, maintain audit trails, and enforce standardized governance across all locations.
AI-driven analytics and search
Centralized video storage also enables advanced analytics capabilities. March Networks integrates AI-powered tools such as AI Smart Search, which allows users to locate relevant footage using natural-language queries across large video archives.
These capabilities leverage technologies, including Amazon S3 Vectors and Amazon Bedrock to support semantic search and AI-driven video intelligence across enterprise-scale datasets.
Conclusion
As organizations generate increasing volumes of video data, scalable cloud infrastructure becomes essential for managing long-term storage and enabling advanced analytics. By building its Cloud Storage platform on AWS, March Networks provides organizations with a durable, secure, and cost-efficient foundation for enterprise video retention.
Services such as Amazon S3, Amazon S3 Glacier, Amazon SQS, Amazon CloudWatch, and AWS Security Token Service support a scalable architecture capable of storing and managing petabytes of video data across distributed environments. This cloud-native approach allows organizations to modernize video infrastructure today while preparing for future AI-driven analytics and operational intelligence.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.