Post Syndicated from Philipp Karg original https://aws.amazon.com/blogs/big-data/how-bmw-group-built-a-serverless-terabyte-scale-data-transformation-architecture-with-dbt-and-amazon-athena/
Businesses increasingly require scalable, cost-efficient architectures to process and transform massive datasets. At the BMW Group, our Cloud Efficiency Analytics (CLEA) team has developed a FinOps solution to optimize costs across over 10,000 cloud accounts. While enabling organization-wide efficiency, the team also applied these principles to the data architecture, making sure that CLEA itself operates frugally. After evaluating various tools, we built a serverless data transformation pipeline using Amazon Athena and dbt.
This post explores our journey, from the initial challenges to our current architecture, and details the steps we took to achieve a highly efficient, serverless data transformation setup.
Challenges: Starting from a rigid and costly setup
In our early stages, we encountered several inefficiencies that made scaling difficult. We were managing complex schemas with wide tables that required significant effort in maintainability. Initially, we used Terraform to create tables and views in Athena, allowing us to manage our data infrastructure as code (IaC) and automate deployments through continuous integration and delivery (CI/CD) pipelines. However, this method slowed us down when changing data models or dealing with schema changes, therefore requiring high development efforts.
As our solution grew, we faced challenges with query performance and costs. Each query scanned large amounts of raw data, resulting in increased processing time and higher Athena costs. We used views to provide a clean abstraction layer, but this masked underlying complexity because seemingly simple queries against these views scanned large volumes of raw data, and our partitioning strategy wasn’t optimized for these access patterns. As our datasets grew, the lack of modularity in our data design increased complexity, making scalability and maintenance increasingly difficult. We needed a solution for pre-aggregating, computing, and storing query results of computationally intensive transformations. The absence of robust testing and lineage solutions made it challenging to identify the root causes of data inconsistencies when they occurred.
As part of our business intelligence (BI) solution, we used Amazon QuickSight to build our dashboards, providing visual insights into our cloud cost data. However, our initial data architecture led to challenges. We were building dashboards on top of large, wide datasets, with some hitting the QuickSight per-dataset SPICE limit of 1 TB. Additionally, during SPICE ingest, our largest datasets required 4–5 hours of processing time due to performing full scans each time, often scanning over a terabyte of data. This architecture wasn’t helping us be more agile and quick while scaling up. The long processing times and storage limitations hindered our ability to provide timely insights and expand our analytics capabilities.
To address these issues, we enhanced the data architecture with AWS Lambda, AWS Step Functions, AWS Glue, and dbt. This tool stack significantly enhanced our development agility, empowering us to quickly modify and introduce new data models. At the same time, we improved our overall data processing efficiency with incremental loads and better schema management.
Solution overview
Our current architecture consists of a serverless and modular pipeline coordinated by GitHub Actions workflows. We chose Athena as our primary query engine for several strategic reasons: it aligns perfectly with our team’s SQL expertise, excels at querying Parquet data directly in our data lake, and alleviates the need for dedicated compute resources. This makes Athena an ideal fit for CLEA’s architecture, where we process around 300 GB daily from a data lake of 15 TB, with our largest dataset containing 50 billion rows across up to 400 columns. The capability of Athena to efficiently query large-scale Parquet data, combined with its serverless nature, enables us to focus on writing efficient transformations rather than managing infrastructure.
The following diagram illustrates the solution architecture.

Using this architecture, we’ve streamlined our data transformation process using dbt. In dbt, a data model represents a single SQL transformation that creates either a table or a view—essentially a building block of our data transformation pipeline. Our implementation includes around 400 such models, 50 data sources, and around 100 data tests. This setup enables seamless updates—whether creating new models, updating schemas, or modifying views—triggered simply by creating a pull request in our source code repository, with the rest handled automatically.
Our workflow automation includes the following features:
- Pull request – When we create a pull request, it’s deployed to our testing environment first. After passing validation and being approved or merged, it’s deployed to production using GitHub workflows. This setup enables seamless model creation, schema updates, or view changes—triggered just by creating a pull request, with the rest handled automatically.
- Cron scheduler – For nightly runs or multiple daily runs to reduce data latency, we use scheduled GitHub workflows. This setup allows us to configure specific models with different update strategies based on data needs. We can set models to update incrementally (processing only new or changed data), as views (querying without materializing data), or as full loads (completely refreshing the data). This flexibility optimizes processing time and resource usage. We can target only specific folders—like source, prepared, or semantic layers—and run the dbt test afterward to validate model quality.
- On demand – When adding new columns or changing business logic, we need to update historical data to maintain consistency. For this, we use a backfill process, which is a custom GitHub workflow created by our team. The workflow allows us to select specific models, include their upstream dependencies, and set parameters like start and end dates. This makes sure that changes are applied accurately across the entire historical dataset, maintaining data consistency and integrity.
Our pipeline is organized into three primary stages—Source, Prepared, and Semantic—each serving a specific purpose in our data transformation journey. The Source stage maintains raw data in its original form. The Prepared stage cleanses and standardizes this data, handling tasks like deduplication and data type conversions. The Semantic stage transforms this prepared data into business-ready models aligned with our analytical needs. An additional QuickSight step handles visualization requirements. To achieve low cost and high performance, we use dbt models and SQL code to manage all transformations and schema changes. By implementing incremental processing strategies, our models process only new or changed data rather than reprocessing the entire dataset with each run.
The Semantic stage (not to be confused with dbt’s semantic layer feature) introduces business logic, transforming data into aggregated datasets that are directly consumable by BMW’s Cloud Data Hub, internal CLEA dashboards, data APIs, or In-Console Cloud Assistant (ICCA) chatbot. The QuickSight step further optimizes data by selecting only necessary columns by using a column-level lineage solution and setting a dynamic date filter with a sliding window to ingest only relevant hot data into SPICE, avoiding unused data in dashboards or reports.
This approach aligns with BMW Group’s broader data strategy, which includes streamlining data access using AWS Lake Formation for fine-grained access control.
Overall, as a high-level structure, we’ve fully automated schema changes, data updates, and testing through GitHub pull requests and dbt commands. This approach enables controlled deployment with robust version control and change management. Continuous testing and monitoring workflows uphold data accuracy, reliability, and quality across transformations, supporting efficient, collaborative model iteration.
Key benefits of the dbt-Athena architecture
To design and manage dbt models effectively, we use a multi-layered approach combined with cost and performance optimizations. In this section, we discuss how our approach has yielded significant benefits in five key areas.
SQL-based, developer-friendly environment
Our team already had strong SQL skills, so dbt’s SQL-centric approach was a natural fit. Instead of learning a new language or framework, developers could immediately start writing transformations using familiar SQL syntax with dbt. This familiarity aligns well with the SQL interface of Athena and, combined with dbt’s added functionality, has increased our team’s productivity.
Behind the scenes, dbt automatically handles synchronization between Amazon Simple Storage Service (Amazon S3), the AWS Glue Data Catalog, and our models. When we need to change a model’s materialization type—for example, from a view to a table—it’s as simple as updating a configuration parameter rather than rewriting code. This flexibility has reduced our development time dramatically, allowed us to focus on building better data models rather than managing infrastructure.
Agility in modeling and deployment
Documentation is crucial for any data platform’s success. We use dbt’s built-in documentation capabilities by publishing them to GitHub Pages, which creates an accessible, searchable repository of our data models. This documentation includes table schemas, relationships between models, and usage examples, enabling team members to understand how models interconnect and how to use them effectively.
We use dbt’s built-in testing capabilities to implement comprehensive data quality checks. These include schema tests that verify column uniqueness, referential integrity, and null constraints, as well as custom SQL tests that validate business logic and data consistency. The testing framework runs automatically on every pull request, validating data transformations at each step of our pipeline. Additionally, dbt’s dependency graph provides a visual representation of how our models interconnect, helping us understand the upstream and downstream impacts of any changes before we implement them. When stakeholders need to modify models, they can submit changes through pull requests, which, after they’re approved and merged, automatically trigger the necessary data transformations through our CI/CD pipeline. This streamlined process enabled us to create new data products within days compared to weeks and reduced ongoing maintenance work by catching issues early in the development cycle.
Athena workgroup separation
We use Athena workgroups to isolate different query patterns based on their execution triggers and purposes. Each workgroup has its own configuration and metric reporting, allowing us to monitor and optimize separately. The dbt workgroup handles our scheduled nightly transformations and on-demand updates triggered by pull requests through our Source, Prepared, and Semantic stages. The dbt-test workgroup executes automated data quality checks during pull request validation and nightly builds. The QuickSight workgroup manages SPICE data ingestion queries, and the Ad-hoc workgroup supports interactive data exploration by our team.
Each workgroup can be configured with specific data usage quotas, enabling teams to implement granular governance policies. This separation provides several benefits: it enables clear cost allocation, provides isolated monitoring of query patterns across different use cases, and helps enforce data governance through custom workgroup settings. Amazon CloudWatch monitoring per workgroup helps us track usage patterns, identify query performance issues, and adjust configurations based on actual needs.
Using QuickSight SPICE
QuickSight SPICE (Super-fast, Parallel, In-memory Calculation Engine) provides powerful in-memory processing capabilities that we’ve optimized for our specific use cases. Rather than loading entire tables into SPICE, we create specialized views on top of our materialized semantic models. These views are carefully crafted to include only the necessary columns, relevant metadata joins, and appropriate time filtering to have only recent data available in dashboards.
We’ve implemented a hybrid refresh strategy for these SPICE datasets: daily incremental updates keep the data fresh, and weekly full refreshes maintain data consistency. This approach strikes a balance between data freshness and processing efficiency. The result is responsive dashboards that maintain high performance while keeping processing costs under control.
Scalability and cost-efficiency
The serverless architecture of Athena eliminates manual infrastructure management, automatically scaling based on query demand. Because costs are based solely on the amount of data scanned by queries, optimizing queries to scan as little data as possible directly reduces our costs. We use the distributed query execution capabilities of Athena through our dbt model structure, enabling parallel processing across data partitions. By implementing effective partitioning strategies and using Parquet file format, we minimize the amount of data scanned while maximizing query performance.
Our architecture offers flexibility in how we materialize data through views, full tables, and incremental tables. With dbt’s incremental models and partitioning strategy, we process only new or modified data instead of entire datasets. This approach has proven highly effective—we’ve observed significant reductions in data processing volume as well as data scanning, particularly in our QuickSight workgroup.
The effectiveness of these optimizations implemented at the end of 2023 is visible in the following diagram, showing costs by Athena workgroups.

The workgroups are illustrated as follows:
- Green (QuickSight): Shows reduced data scanning post-optimization.
- Light blue (Ad-hoc): Varies based on analysis needs.
- Dark blue (dbt): Maintains consistent processing patterns
- Orange (dbt-test): Shows regular, efficient test execution.
The increased dbt workload costs directly correlate with decreased QuickSight costs, reflecting our architectural shift from using complex views in QuickSight workgroups (which previously masked query complexity but led to repeated computations) to using dbt for materializing these transformations. Although this increased the dbt workload, the overall cost-efficiency improved significantly because materialized tables reduced redundant computations in QuickSight. This demonstrates how our optimization strategies successfully manage growing data volumes while achieving net cost reduction through efficient data materialization patterns.
Conclusion
Our data architecture uses dbt and Athena to provide a scalable, cost-efficient, and flexible framework for building and managing data transformation pipelines. Athena’s ability to query data directly in Amazon S3 alleviates the need to move or copy data into a separate data warehouse, and its serverless model and dbt’s incremental processing minimize both operational overhead and processing costs. Given our team’s strong SQL expertise, expressing these transformations in SQL through dbt and Athena was a natural choice, enabling rapid model development and deployment. With dbt’s automatic documentation and lineage, troubleshooting and identifying data issues is simplified, and the system’s modularity allows for quick adjustments to meet evolving business needs.
Starting with this architecture is quick and straightforward: all that is needed is the dbt-core and dbt-athena libraries, and Athena itself requires no setup, because it’s a fully serverless service with seamless integration with Amazon S3. This architecture is ideal for teams looking to rapidly prototype, test, and deploy data models, optimizing resource usage, accelerating deployment, and providing high-quality, accurate data processing.
For those interested in a managed solution from dbt, see From data lakes to insights: dbt adapter for Amazon Athena now supported in dbt Cloud.
About the Authors
Philipp Karg is a Lead FinOps Engineer at BMW Group and has a strong background in data engineering, AI, and FinOps. He focuses on driving cloud efficiency initiatives and fostering a cost-aware culture within the company to leverage the cloud sustainably.
 Selman Ay is a Data Architect specializing in end-to-end data solutions, architecture, and AI on AWS. Outside of work, he enjoys playing tennis and engaging outdoor activities.
 Cizer Pereira is a Senior DevOps Architect at AWS Professional Services. He works closely with AWS customers to accelerate their journey to the cloud. He has a deep passion for cloud-based and DevOps solutions, and in his free time, he also enjoys contributing to open source projects.


 Lakshmi Nair is a Senior Analytics Specialist Solutions Architect at AWS. She specializes in designing advanced analytics systems across industries. She focuses on crafting cloud-based data platforms, enabling real-time streaming, big data processing, and robust data governance. She can be reached via
 Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He is also the author of the book
 Sakti Mishra is a Principal Data and AI Solutions Architect at AWS, where he helps customers modernize their data architecture and define end-to end-data strategies, including data security, accessibility, governance, and more. He is also the author of
 Daiyan Alamgir is a Principal Frontend Engineer on the Amazon SageMaker Unified Studio team based in New York.
 Vipin Mohan is a Principal Product Manager at AWS, leading the launch of generative AI capabilities in Amazon SageMaker Unified Studio. He is committed to shaping impactful products by working backward from customer insights, championing user-focused solutions, and delivering scalable results.
 Chanu Damarla is a Principal Product Manager on the Amazon SageMaker Unified Studio team. He works with customers around the globe to translate business and technical requirements into products that delight customers and enable them to be more productive with their data, analytics, and AI.


 Yonatan Dolan is a Principal Analytics Specialist at Amazon Web Services. Yonatan is an Apache Iceberg evangelist.
 Haya Stern is a Senior Director of Data at Natural Intelligence. She leads the development of NI’s large-scale data platform, with a focus on enabling analytics, streamlining data workflows, and improving dev efficiency. In the past year, she led the successful migration from the previous data architecture to a modern lake house based on Apache Iceberg and Snowflake.
 Data Architect at Natural Intelligence with ten years of experience architecting large‑scale big‑data platforms, now focused on developing intelligent agent systems that turn complex data into real‑time business insight.
 Michał Urbanowicz is a Cloud Data Engineer at Natural Intelligence with expertise in migrating data warehouses and implementing robust retention, cleanup, and monitoring processes to ensure scalability and reliability. He also develops automations that streamline and support campaign management operations in cloud-based environments.


 Sandeep Adwankar is a Senior Product Manager at AWS. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that enable customers to improve how they manage, secure, and access data.
 Srividya Parthasarathy is a Senior Big Data Architect on the AWS Lake Formation team. She enjoys building data mesh solutions and sharing them with the community.


 Sam Selvan is a Principal Specialist Solution Architect with Amazon OpenSearch Service.
 Jagadish Kumar (Jag) is a Senior Specialist Solutions Architect at AWS focused on Amazon OpenSearch Service. He is deeply passionate about Data Architecture and helps customers build analytics solutions at scale on AWS.
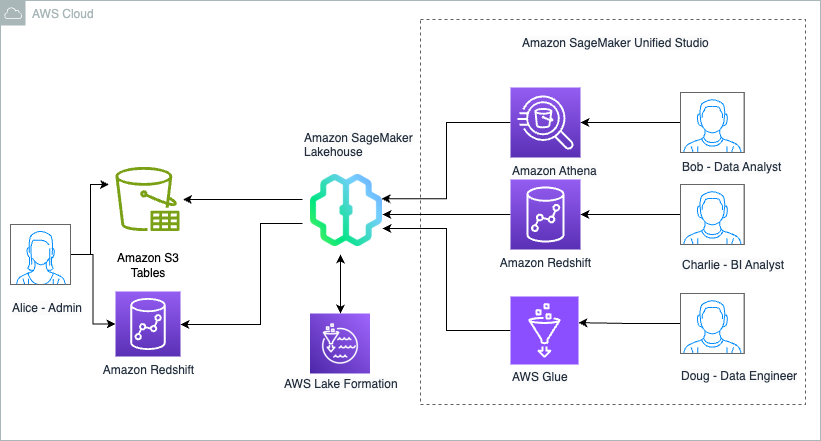


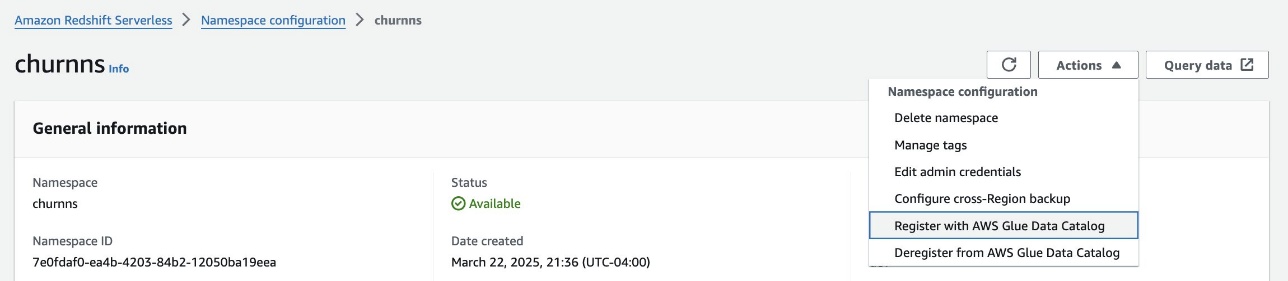


 Charlie can now further update the SQL query and use it to power QuickSight dashboards that can be shared with Sales team members.

 Sandeep Adwankar is a Senior Technical Product Manager at AWS. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that enable customers to improve how they manage, secure, and access data.
 Srividya Parthasarathy is a Senior Big Data Architect on the AWS Lake Formation team. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.




 BP Yau is a Sr Partner Solutions Architect at AWS. His role is to help customers architect big data solutions to process data at scale. Before AWS, he helped Amazon.com Supply Chain Optimization Technologies migrate its Oracle data warehouse to Amazon Redshift and build its next generation big data analytics platform using AWS technologies.
 Ali Alladin is the Senior Director of Product Management and Partner Solutions at ThoughtSpot. In this role, Ali oversees Cloud Engineering and Operations, ensuring seamless integration and optimal performance of ThoughtSpot’s cloud-based services. Additionally, Ali spearheads the development of AI-powered solutions in augmented and embedded analytics, collaborating closely with technology partners to drive innovation and deliver cutting-edge analytics capabilities. With a robust background in product management and a keen understanding of AI technologies, Ali is dedicated to pushing the boundaries of what’s possible in the analytics space, helping organizations harness the full potential of their data.


 Ramesh H Singh is a Senior Product Manager Technical (External Services) at AWS in Seattle, Washington, currently with the Amazon SageMaker team. He is passionate about building high-performance ML/AI and analytics products that enable enterprise customers to achieve their critical goals using cutting-edge technology. Connect with him on
 Pradeep Misra is a Principal Analytics Solutions Architect at AWS. He works across Amazon to architect and design modern distributed analytics and AI/ML platform solutions. He is passionate about solving customer challenges using data, analytics, and AI/ML. Outside of work, Pradeep likes exploring new places, trying new cuisines, and playing board games with his family. He also likes doing science experiments, building LEGOs and watching anime with his daughters.
 Rajat Mathur is a Software Development Manager at AWS, leading the Amazon DataZone and SageMaker Unified Studio engineering teams. His team designs, builds, and operates services which make it faster and easier for customers to catalog, discover, share, and govern data. With deep expertise in building distributed data systems at scale, Rajat plays a key role in advancing AWS’s data analytics and AI/ML capabilities.
 Jie Lan is a Software Engineer at AWS based in New York, where he works on the Amazon SageMaker team. He is passionate about developing cutting-edge solutions in the big data and AI space, helping customers leverage cloud technology to solve complex problems.


 Lorenzo Nicora works as Senior Streaming Solution Architect at AWS, helping customers across EMEA. He has been building cloud-centered, data-intensive systems for over 25 years, working across industries both through consultancies and product companies. He has used open-source technologies extensively and contributed to several projects, including Apache Flink, and is the maintainer of the Flink Prometheus connector.
 Francisco Morillo is a Senior Streaming Solutions Architect at AWS. Francisco works with AWS customers, helping them design real-time analytics architectures using AWS services, supporting Amazon MSK and Amazon Managed Service for Apache Flink. He is also a main contributor to the Flink Prometheus connector.




 Sotaro Hikita is an Analytics Solutions Architect. He supports customers across a wide range of industries in building and operating analytics platforms more effectively. He is particularly passionate about big data technologies and open source software.









 Sandhya Edupuganti is a Senior Engineering Leader spearheading Amazon DataZone (aka) SageMaker Catalog. She is based in Seattle Metro area and has been with Amazon for over 17 years leading strategic initiatives in Amazon Advertising, Amazon-Retail, Latam-Expansion and AWS Analytics.


 Chris Li is an Enterprise Support manager at AWS. He leads a team of Technical Account Managers to solve complex customer problems and implement well-structured solutions.


 G2 Krishnamoorthy is VP of Analytics, leading AWS data lake services, data integration, Amazon OpenSearch Service, and Amazon QuickSight. Prior to his current role, G2 built and ran the Analytics and ML Platform at Facebook/Meta, and built various parts of the SQL Server database, Azure Analytics, and Azure ML at Microsoft.
 Rahul Pathak is VP of Relational Database Engines, leading Amazon Aurora, Amazon Redshift, and Amazon QLDB. Prior to his current role, he was VP of Analytics at AWS, where he worked across the entire AWS database portfolio. He has co-founded two companies, one focused on digital media analytics and the other on IP-geolocation.


