We are making IAM Access Analyzer even more powerful, extending custom policy checks and adding easy access to guidance that will help you to fine-tune your IAM policies. Both of these new features build on the Custom Policy Checks and the Unused Access analysis that were launched at re:Invent 2023. Here’s what we are launching:
New Custom Policy Checks – Using the power of automated reasoning, the new checks help you to detect policies that grant access to specific, critical AWS resources, or that grant any type of public access. Both of the checks are designed to be used ahead of deployment, possibly as part of your CI/CD pipeline, and will help you proactively detect updates that do not conform to your organization’s security practices and policies.
Guided Revocation – IAM Access Analyzer now gives you guidance that you can share with your developers so that they can revoke permissions that grant access that is not actually needed. This includes unused roles, roles with unused permissions, unused access keys for IAM users, and unused passwords for IAM users. The guidance includes the steps needed to either remove the extra items or to replace them with more restrictive ones.
New Custom Policy Checks The new policy checks can be invoked from the command line or by calling an API function. The checks examine a policy document that is supplied as part of the request and return a PASS or FAIL value. In both cases, PASS indicates that the policy document properly disallows the given access, and FAIL indicates that the policy might allow some or all of the permissions. Here are the new checks:
Check No Public Access – This check operates on a resource policy, and checks to see if the policy grants public access to a specified resource type. For example, you can check a policy to see if it allows public access to an S3 bucket by specifying the AWS::S3::Bucket resource type. Valid resource types include DynamoDB tables and streams, EFS file systems, OpenSearch domains, Kinesis streams and stream consumers, KMS keys, Lambda functions, S3 buckets and access points, S3 Express directory buckets, S3 Outposts buckets and access points, Glacier, Secrets Manager secrets, SNS topics and queues, and IAM policy documents that assume roles. The list of valid resource types will expand over time and can be found in the CheckNoPublicAccess documentation,
{
    "result": "FAIL",
    "message": "The resource policy grants public access for the given resource type.",
    "reasons": [
        {
            "description": "Public access granted in the following statement with sid: SqsResourcePolicy.",
            "statementIndex": 0,
            "statementId": "SqsResourcePolicy"
        }
    ]
}
I edit the policy to remove the access grant and try again, and this time the check passes:
{
    "result": "PASS",
    "message": "The resource policy does not grant public access for the given resource type."
}
Check Access Not Granted – This check operates on a single resource policy or identity policy at a time. It also accepts an list of actions and resources, both in the form that are acceptable as part of an IAM policy. The check sees if the policy grants unintended access to any of the resources in the list by way of the listed actions. For example, this check could be used to make sure that a policy does not allow a critical CloudTrail trail to be deleted:
IAM Access Analyzer indicates that the check fails:
{
    "result": "FAIL",
    "message": "The policy document grants access to perform one or more of the listed actions or resources.",
    "reasons": [
        {
            "description": "One or more of the listed actions or resources in the statement with index: 0.",
            "statementIndex": 0
        }
    ]
}
I fix the policy and try again, and this time the check passes, indicating that the policy does not grant access to the listed resources:
{
    "result": "PASS",
    "message": "The policy document does not grant access to perform the listed actions or resources."
}
Guided Revocation In my earlier post I showed you how IAM Access Analyzer discovers and lists IAM items that grant access which is not actually needed. With today’s launch, you now get guidance to help you (or your developer team) to resolve these findings. Here are the latest findings from my AWS account:
Some of these are leftovers from times when I was given early access to a service so that I could use and then blog about it; others are due to my general ineptness as a cloud admin! Either way, I need to clean these up. Let’s start with the second one, Unused access key. I click on the item and can see the new Recommendations section at the bottom:
I can follow the steps and delete the access key or I can click Archive to remove the finding from the list of active findings and add it to the list of archived ones. I can also create an archive rule that will do the same for similar findings in the future. Similar recommendations are provided for unused IAM users, IAM roles, and passwords.
Now let’s take a look at a finding of Unused permissions:
The recommendation is to replace the existing policy with a new one. I can preview the new policy side-by-side with the existing one:
As in the first example I can follow the steps or I can archive the finding.
The findings and the recommendations are also available from the command line. I generate the recommendation by specifying an analyzer and a finding from it:
Security is our top priority at Amazon Web Services (AWS), and today, we’re launching two capabilities to help you strengthen the security posture of your AWS accounts:
Second, we started to enforce MFA on your root users, starting with the most sensitive one: the root user of your management account in an AWS Organization. We will continue to roll out this change on your other accounts during the rest of the year.
MFA is one of the simplest and most effective ways to enhance account security, offering an additional layer of protection to help prevent unauthorized individuals from gaining access to systems or data.
MFA with passkey for your root and IAM users Passkey is a general term used for the credentials created for FIDO2 authentication.
A passkey is a pair of cryptographic keys generated on your client device when you register for a service or a website. The key pair is bound to the web service domain and unique for each one.
The public part of the key is sent to the service and stored on their end. The private part of the key is either stored in a secured device, such as a security key, or securely shared across your devices connected to your user account when you use cloud services, such as iCloud Keychain, Google accounts, or a password manager such as 1Password.
Typically, the access to the private part of the key is protected by a PIN code or a biometric authentication, such as Apple Face ID or Touch ID or Microsoft Hello, depending on your devices.
When I try to authenticate on a service protected with passkeys, the service sends a challenge to my browser. The browser then requests my device sign the challenge with my private key. This triggers a PIN or biometric authentication to access the secured storage where the private key is stored. The browser returns the signature to the service. When the signature is valid, it confirms I own the private key that matches the public key stored on the service, and the authentication succeeds.
Passkeys can be used to replace passwords. However, for this initial release, we choose to use passkeys as a second factor authentication, in addition to your password. The password is something you know, and the passkey is something you have.
Passkeys are more resistant to phishing attacks than passwords. First, it’s much harder to gain access to a private key protected by your fingerprint, face, or a PIN code. Second, passkeys are bound to a specific web domain, reducing the scope in case of unintentional disclosure.
As an end user, you will benefit from the convenience of use and easy recoverability. You can use the built-in authenticators in your phones and laptops to unlock a cryptographically secured credential to your AWS sign-in experience. And when using a cloud service to store the passkey (such as iCloud keychain, Google accounts, or 1Password), the passkey can be accessed from any of your devices connected to your passkey provider account. This helps you to recover your passkey in the unfortunate case of losing a device.
How to enable passkey MFA for an IAM user To enable passkey MFA, I navigate to the AWS Identity and Access Management (IAM) section of the console. I select a user, and I scroll down the page to the Multi-factor authentication (MFA) section. Then, I select Assign MFA device.
On the next page, I enter an MFA device name, and I select Passkey or security key. Then, I select next.
When using a password manager application that supports passkeys, it will pop up and ask if you want to generate and store a passkey using that application. Otherwise, your browser will present you with a couple of options. The exact layout of the screen depends on the operating system (macOS or Windows) and the browser you use. Here is the screen I see on macOS with a Chromium-based browser.
The rest of the experience depends on your selection. iCloud Keychain will prompt you for a Touch ID to generate and store the passkey.
In the context of this demo, I want to show you how to bootstrap the passkey on another device, such as a phone. I therefore select Use a phone, tablet, or security key instead. The browser presents me with a QR code. Then, I use my phone to scan the QR code. The phone authenticates me with Face ID and generates and stores the passkey.
This QR code-based flow allows a passkey from one device to be used to sign in on another device (a phone and my laptop in my demo). It is defined by the FIDO specification and known as cross device authentication (CDA).
When everything goes well, the passkey is now registered with the IAM user.
Note that we don’t recommend using IAM users to authenticate human beings to the AWS console. We recommend configuring single sign-on (SSO) with AWS IAM Identity Center instead.
What’s the sign-in experience? Once MFA is enabled and configured with a passkey, I try to sign in to my account.
The user experience differs based on the operating system, browser, and device you use.
For example, on macOS with iCloud Keychain enabled, the system prompts me for a touch on the Touch ID key. For this demo, I registered the passkey on my phone using CDA. Therefore, the system asks me to scan a QR code with my phone. Once scanned, the phone authenticates me with Face ID to unlock the passkey, and the AWS console terminates the sign-in procedure.
Verifying that the most privileged users in AWS are protected with MFA is just the latest step in our commitment to continuously enhance the security posture of AWS customers.
We started with your most sensitive account: your management account for AWS Organizations. The deployment of the policy is progressive, with just a few thousand accounts at a time. Over the coming months, we will progressively deploy the MFA enforcement policy on root users for the majority of the AWS accounts.
When you don’t have MFA enabled on your root user account, and your account is updated, a new message will pop up when you sign in, asking you to enable MFA. You will have a grace period, after which the MFA becomes mandatory.
You can start to use passkeys for multi-factor authentication today in all AWS Regions, except in China.
We’re enforcing the use of multi-factor authentication in all AWS Regions, except for the two regions in China (Beijing, Ningxia) and for AWS GovCloud (US), because the AWS accounts in these Regions have no root user.
AWS CodeBuild now supports managed self-hosted GitHub Action runners, allowing you to build powerful CI/CD capabilities right beside your code and quickly implement a build, test and deploy pipeline. Last year AWS announced that customers can define their GitHub Actions steps within any phase of a CodeBuild buildspec file but with a self-hosted runner, jobs execute from GitHub Actions on GitHub.com to a system you deploy and manage.
For customers managing their self-hosted runners on their own infrastructure, CodeBuild can now provide a secure, scalable and lower latency solution. In addition, CodeBuild managed self-hosted GitHub Action runners bring features, such as:
Available compute platforms including AWS Lambda, Windows, Linux, Linux GPU-enhanced and AWS Graviton Processors (Arm-based instances).
With the compute options available, customers can now run tests on hardware and operating system combinations that closely match production and reduce manual operational tasks by shifting the management of the runners to AWS.
In this blog, I will explore how AWS managed GitHub Action self-hosted runners work by building and deploying an application to AWS using GitHub Actions.
Architecture overview
The architecture of what I’ll be building can be seen below:
The architecture above shows how a developer pushes code changes to GitHub. This triggers CodeBuild to detect the update. CodeBuild then runs the defined GitHub Action Workflow, which builds and deploys it to AWS Lambda.
Step 1. Build a AWS Lambda Function
I’ll start with a simple application to demonstrate how to build and deploy an application on AWS via a Managed Self-Hosted GitHub Actions runner. We’ve written before about why AWS is the best place to run Rust, Amazon CTO Werner Vogels has been an outspoken advocate for exploring energy-efficient programming languages like Rust and AWS have great guides on using Rust to build on AWS such as:
From the above cloned repository, install Cargo Lambda:For macOS & Linux:
brew tap cargo-lambda/cargo-lambda
brew install cargo-lambda
Windows users can follow the guide to see all the ways that you can install Cargo Lambda in your system.
Use Cargo lambda to create a new project
cargo lambda new new-lambda-project && cd new-lambda-project
It’s now possible to explore the project, in this case I am using JetBrains RustRover with Amazon Q Developer installed to increase my productivity while working on the application:
Figure 3. JetBrains RustRover with Amazon Q Developer
I will create a new CodeBuild project as per the documentation to connect CodeBuild to our GitHub repository and correctly configure a webhook to trigger the GitHub Actions.
For Repository, choose Repository in my GitHub account.
For Repository URL, enter https://github.com/user-name/repository-name.
In Primary source webhook events:
For Webhook – optional, select Rebuild every time a code change is pushed to this repository.
For Event type, select WORKFLOW_JOB_QUEUED. Once this is enabled, builds will only be triggered by GitHub Actions workflow jobs events.
Figure 4. WORKFLOW_JOB_QUEUED Event Type
In Environment:
Choose a supported Environment image and Compute. Note that you have the option to override the image and instance settings by using a label in your GitHub Actions workflow YAML.
In Buildspec:
Note that your Buildspec will be ignored. Instead, CodeBuild will override it to use commands that will setup the self-hosted runner. This project’s primary responsibility is to set up a self-hosted runner in CodeBuild to run GitHub Actions workflow jobs.
Continue with the remaining default options and select Create build project.
CodeBuild Service Role Permissions
In order for the CodeBuild service role to be able to successfully create and deploy a Lambda function, the service role will require the necessary permissions. The Service role can be seen when editing the CodeBuild project:
Note that I do not need to manage IAM permissions outside of our AWS Account, for example GitHub does not need to know about our AWS permissions.
Step 3. Create a GitHub Action Workflow
GitHub Actions is a continuous integration and continuous deliver (CI/CD) platform that provides automation through building, testing and deploying applications. In this section we will create a GitHub Action Workflow to build and deploy our Lambda.
Navigate back to our GitHub project create a workflow within the .github/workflows directory, the Simple Workflow is a good starting point:
Figure 6. Create a Simple Workflow
Update the Job to include the tooling required to build our Rust Lambda function, the details can be found in the GitHub Actions section. Our workflow file should now look like this:
The above GitHub Actions Workflow currently runs on GitHub; However, I now want to make two further changes:
Define an AWS CodeBuild runner
Define Build and Deploy Lambda steps
Define an AWS CodeBuild runner
A GitHub Actions workflow is made up of one or more jobs, each job runs in a runner environment specified by runs-on. The value for runs-on to specify CodeBuild as a runner takes the format:
I will update the <CodeBuildProjectName> to the CodeBuild project name that was entered in Step2, e.g. “GitHubActionsDemo”.
When configuring CodeBuild as a runner environment, BuildSpecs are ignored. In order to define the specification of our build environments it is possible to pass in variables including:
When I commit changes to the workflow to the main branch it will trigger the GitHub Action.
Step 4. Testing our GitHub Action Workflow.
The GitHub Action is currently triggered on all push and pull requests to main branch:
Figure 7. Trigger a build
Note that GitHub is where the CI/CD process is being driven, the build logs are available in GitHub as the job is running:
Figure 8. GitHub Action Logs
As the build progresses through the deployment step, the details of the Lambda function deployed are shown:
Figure 9. Deployment ARN
Navigating back to the AWS Console, the deployed Lambda Function can be seen:
Figure 10. Lambda Deployed
And finally, opening the CodeBuild console, it’s possible to observe the status of the Managed GitHub Actions Runner, the build number and also the duration:
Figure 11. Lambda Deployed via Managed Self-Hosted GitHub Action runner
Clean Up
To avoid incurring future charges:
Delete the Lambda created via the deployment in Step 4.
Delete the CodeBuild Project created in Step 2.
Conclusion
As I’ve shown in this blog, setting up GitHub Actions Workflows that run on AWS is now even easier to allow CodeBuild projects to receive GitHub Actions workflow job events and run them on CodeBuild ephemeral hosts. AWS customers can take advantage of natively integrating with AWS and providing security and convenience through features such as defining service role permissions with AWS IAM or passing credentials as environment variables to build jobs with AWS Secrets Manager.
Being able to use CodeBuild’s reserved capacity allows you to provision a fleet of CodeBuild hosts that persist your build environment. These hosts remain available to receive subsequent build requests, which reduces build start-up latencies but also make it possible to compile your software within your VPC and access resources such as Amazon Relational Database Service, Amazon ElastiCache, or any service endpoints that are only reachable from within a specific VPC.
CodeBuild-hosted GitHub Actions runners are supported in all CodeBuild regions and customers managing their CI/CD processes via GitHub Actions can use the compute platforms CodeBuild offers, including Lambda, Windows, Linux, Linux GPU-enhanced and Arm-based instances powered by AWS Graviton Processors.
As a developer, marketing professional, or someone in the communications space, you’re likely familiar with the importance of SMS messaging in engaging customers and driving valuable interactions. However, you may have also encountered the growing challenge of artificially inflated traffic (AIT), also known as SMS pumping. A new report co-authored by Enea revealed that AIT is so widespread within the SMS ecosystem that 19.8B-35.7B fraudulent messages were sent by bad actors in 2023, incurring substantial costs of over $1 billion. In this blog post, we’ll explore how you can use Protect configurations, a powerful set of capabilities within Amazon Pinpoint SMS, that provides granular control over which destination countries your SMS, MMS, and voice messages can be sent to.
” width=”1252″ height=”889″>
What is SMS Pumping, aka Artificially Inflated Traffic (AIT)?
AIT, or SMS pumping, is a type of fraud where bad actors use bots to generate large volumes of fake SMS traffic. These bots target businesses’ whose websites, apps, and other assets have forms or other mechanisms that trigger SMS being sent out. Common use cases for SMS such as one-time passwords (OTPs), app download links, promotion signups, etc. are all targets for these bad actors to “pump” SMS and send out fraudulent messages. The goal is to artificially inflate the number of SMS messages a business sends, resulting in increased costs and a negative impact on the sender’s reputation. In the realm of SMS-based artificially inflated traffic (AIT), the prevalent method for bad actors to profit involves colluding with parties in the SMS delivery chain to receive a portion of the revenue generated from each fraudulent message sent.
” width=”1280″ height=”720″>
AIT poses several challenges for businesses:
Overspending: The fake SMS traffic generated by AIT bots results in businesses paying for messages that yield no actual results.
Interrupted service: Large volumes of AIT can force businesses to temporarily halt SMS services, disrupting legitimate customer communications.
Diverted focus: Dealing with AIT can shift businesses’ attention away from core operations and priorities.
Reduced deliverability rates due to the messages never being interacted with and/or large volumes of SMS being sent quickly.
How does Protect mitigate AIT?
Amazon Pinpoint’s Protect feature allows you to control which countries you can send messages to. This is beneficial if your customers are located in specific countries.
With Protect, you can create a list of country rules that either allow or block messages to each destination country. These country rules can be applied to SMS, MMS, and voice messages sent from your AWS account. The Protect configurations you create enable precise control over which destination countries your messages can be sent to. This helps mitigate the impact of AIT by allowing you to tailor where you do or do not send.
Protect offers flexibility in how the country rules are applied. You can apply them at the account level, the configuration set level, or the individual message level. This enables you to customize your AIT mitigation strategy to best fit your business needs and messaging patterns.
By leveraging Protect within Amazon Pinpoint, you can help ensure the integrity and cost-effectiveness of your SMS, MMS, and voice communications.
Account-level Protect Configuration
The simplest approach is to create a Protect configuration and associate it as the account default. This means the allow/block rules defined in that configuration will be applied across all messages sent from your account, unless overridden. This is an effective option if you only need one set of country rules applied universally.
Configuration set-specific Protect configuration
You can associate a Protect configuration with one or more of your Pinpoint SMS configuration sets. This allows you to apply different country rules to distinct messaging flows or use cases within your application without changing your existing code if you are already using Config Sets. It also enables more detailed logging and monitoring of the Protect configuration’s impact, such as:
Error Logs: Logging of any errors or issues encountered when messages are sent, providing insights into how the Protect configuration is affecting message delivery.
Audit Logs: Records of all configuration changes, access attempts, and other relevant activities related to the Protect configuration, allowing for comprehensive auditing and monitoring.
Usage Metrics: Tracking of usage statistics, such as the number of messages sent to different countries, the impact of the Protect configuration on message volumes, and other usage-related data.
Compliance and Policy Enforcement Logs: Documentation of how the Protect configuration is enforcing compliance with messaging policies and regulations, including any instances where messages are blocked or allowed based on the configuration rules.
Dynamic Protect configuration per message
If your needs are even more specific, you can create a Protect configuration without any association, and then specify its ID when sending messages via the Pinpoint APIs (e.g. SendMediaMessage, SendTextMessage, SendVoiceMessage). This gives you the ability to dynamically choose the Protect configuration to apply for each individual message, providing the ultimate flexibility.
Regardless of the approach, the core benefit of Protect configurations is the ability to precisely control which destination countries your messages may be sent to. Blocking countries where you don’t have a presence or where SMS pricing is high eliminates your exposure to fraudulent AIT traffic originating from those regions. This helps protect your messaging budget, maintain service continuity, and focus your efforts on legitimate customer interactions.
Who should use Protect configurations?
Protect configurations are designed to benefit a wide range of AWS customers, particularly those who:
Send SMS messages to a limited number of countries: If your business primarily operates in a few specific countries, Protect configurations can help you easily block SMS messages to countries where you don’t have a presence, reducing the risk of AIT.
Have experienced AIT issues in the past: If your business has been a target of SMS pumping, Protect configurations can help you regain control over your SMS communications and prevent future AIT attacks.
Want to proactively protect their SMS messaging: Even if you haven’t encountered AIT issues yet, Protect configurations can help you stay ahead of the curve and maintain the integrity of your SMS communications.
How to create a country rules list with Protect configuration
To begin building a list of country rules that allow or block messages to specific destination countries, you start by creating a new Protect configuration. There are two ways to accomplish this, either by using the console, or the API.
Option 1 – Using the AWS Console
Console Scenario:My account is out of the sandbox and I only want to send to 1 country – United Kingdom (iso:GB) using the SenderID “DEMOTP”.
At a high level, we will follow the three steps outlined below for each method. In our examples, we used a SenderID as our Originator. However, it should be noted that the same process can be achieved using any originator you’d like. i.e. SenderID, Phone pool, Phone number, 10DLC, short code, etc.
Create SenderID (Optional if you already have one)
Select all countries by toggling checkbox in search bar
” width=”863″ height=”521″>
Search for Country=United Kingdom then deselect United Kingdom
” width=”865″ height=”582″>
Set as Account Default and select Create protect configuration
” width=”1497″ height=”1173″>
3) Send a test message with SMS simulator
Note: The Pinpoint SMS Simulator provides special phone numbers you can use to send test text messages and receive realistic event records, all within the confines of the Amazon Pinpoint service. These simulator phone numbers are designed to stay entirely within the Pinpoint SMS ecosystem, ensuring your test messages don’t get sent over the carrier network.
You can use these simulator phone numbers to send both SMS and MMS messages, allowing you to thoroughly validate your message content, workflow, and event handling. The responses you receive back will mimic either success or fail depending on which destination simulator number you send to.
For Originator, Choose Sender ID, and select your Sender ID created from earlier.
Under Destination number, select Simulator numbers and choose United Kingdom (GB). Enter a test message in the Message body.
Finally, choose send test message. This should prompt a green “Success” banner at the top of your page.
” width=”1336″ height=”1313″>
Conversely, follow the previous test message steps, and instead attempt to send to anywhere other than the United Kingdom (GB). In this example, Australia (AU)
As shown below in the screenshot this one is blocked since you have configured to only send to GB.
” width=”1333″ height=”1364″>
Option 2 – Using the V2 API and CLI
V2 API Scenario: My account is out of the sandbox and I want to BLOCK only 1 country – Australia (AU) while using the SenderID “DEMOTP”.
1) Create SenderID for GB
Note: before using the CLI remember to configure your access and secret key using
aws configure
Windows users should use PowerShell over cmd to test
Use RequestSenderId to create the same Sender Id as previously made via the console.
{
An error occurred (ConflictException) when calling the
SendTextMessage operation: Conflict Occurred -
Reason="DESTINATION_COUNTRY_BLOCKED_BY_PROTECT_CONFIGURATION" ResourceType="protect-configuration" ResourceId="string"
}
Conclusion
As SMS messaging continues to play a crucial role in customer engagement and authentication, protecting your communications from AIT is more important than ever. Amazon Pinpoint Protect provides a powerful and user-friendly solution to help you mitigate the impact of SMS pumping, ensuring the integrity of your SMS channels and preserving your business’ reputation and resources. Whether you’re a small business or a large enterprise, Pinpoint Protect is a valuable tool to have in your arsenal as you navigate the evolving landscape of SMS messaging.
To get started with Pinpoint SMS Protect, visit the Amazon Pinpoint SMS documentation or reach out to your AWS account team. And don’t forget to let us know in the comments how Protect configurations has helped you combat AIT and strengthen your SMS communications.
A few resources to help you plan for your SMS program:
The V2 API for SMS and Voice has many more useful actions not possible with the V1 API so we encourage you to explore how it can further help you simplify and automate your applications.
Brett Ezell is your friendly neighborhood Solutions Architect at AWS, where he specializes in helping customers optimize their SMS and email campaigns using Amazon Pinpoint and Amazon Simple Email Service. As a former US Navy veteran, Brett brings a unique perspective to his work, ensuring customers receive tailored solutions to meet their needs. In his free time, Brett enjoys live music, collecting vinyl, and the challenges of a good workout. And, as a self-proclaimed comic book aficionado, he can often be found combing through his local shop for new books to add to his collection.
With AWS Audit Manager, you can map your compliance requirements to AWS usage data and continually audit your AWS usage as part of your risk and compliance assessment. Today, Audit Manager introduces a common control library that provides common controls with predefined and pre-mapped AWS data sources.
The common control library is based on extensive mapping and reviews conducted by AWS certified auditors, verifying that the appropriate data sources are identified for evidence collection. Governance, Risk and Compliance (GRC) teams can use the common control library to save time time when mapping enterprise controls into Audit Manager for evidence collection, reducing their dependence on information technology (IT) teams.
Using the common control library, you can view the compliance requirements for multiple frameworks (such as PCI or HIPAA) associated with the same common control in one place, making it easier to understand your audit readiness across multiple frameworks simultaneously. In this way, you don’t need to implement different compliance standard requirements individually and then review the resulting data multiple times for different compliance regimes.
Additionally, by using controls from this library, you automatically inherit improvements as Audit Manager updates or adds new data sources, such as additional AWS CloudTrail events, AWS API calls, AWS Config rules, or maps additional compliance frameworks to common controls. This eliminates the efforts required by GRC and IT teams to constantly update and manage evidence sources and makes it easier to benefit from additional compliance frameworks that Audit Manager adds to its library.
Let’s see how this works in practice with an example.
Using AWS Audit Manager common control library A common scenario for an airline is to implement a policy so that their customer payments, including in-flight meals and internet access, can only be taken via credit card. To implement this policy, the airline develops an enterprise control for IT operations that says that “customer transactions data is always available.” How can they monitor whether their applications on AWS meet this new control?
Acting as their compliance officer, I open the Audit Manager console and choose Control library from the navigation bar. The control library now includes the new Common category. Each common control maps to a group of core controls that collect evidence from AWS managed data sources and makes it easier to demonstrate compliance with a range of overlapping regulations and standards. I look through the common control library and search for “availability.” Here, I realize the airline’s expected requirements map to common control High availability architecture in the library.
I expand the High availability architecture common control to see the underlying core controls. There, I notice this control doesn’t adequately meet all the company’s needs because Amazon DynamoDB is not in this list. DynamoDB is a fully managed database, but given extensive usage of DynamoDB in their application architecture, they definitely want their DynamoDB tables to be available when their workload grows or shrinks. This might not be the case if they configured a fixed throughput for a DynamoDB table.
I look again through the common control library and search for “redundancy.” I expand the Fault tolerance and redundancy common control to see how it maps to core controls. There, I see the Enable Auto Scaling for Amazon DynamoDB tables core control. This core control is relevant for the architecture that the airline has implemented but the whole common control is not needed.
Additionally, common control High availability architecture already includes a couple of core controls that check that Multi-AZ replication on Amazon Relational Database Service (RDS) is enabled, but these core controls rely on an AWS Config rule. This rule doesn’t work for this use case because the airline does not use AWS Config. One of these two core controls also uses a CloudTrail event, but that event does not cover all scenarios.
As the compliance officer, I would like to collect the actual resource configuration. To collect this evidence, I briefly consult with an IT partner and create a custom control using a Customer managed source. I select the api-rds_describedbinstances API call and set a weekly collection frequency to optimize costs.
Implementing the custom control can be handled by the compliance team with minimal interaction needed from the IT team. If the compliance team has to reduce their reliance on IT, they can implement the entire second common control (Fault tolerance and redundancy) instead of only selecting the core control related to DynamoDB. It might be more than what they need based on their architecture, but the acceleration of velocity and reduction of time and effort for both the compliance and IT teams is often a bigger benefit than optimizing the controls in place.
I now choose Framework library in the navigation pane and create a custom framework that includes these controls. Then, I choose Assessments in the navigation pane and create an assessment that includes the custom framework. After I create the assessment, Audit Manager starts collecting evidence about the selected AWS accounts and their AWS usage.
By following these steps, a compliance team can precisely report on the enterprise control “customer transactions data is always available” using an implementation in line with their system design and their existing AWS services.
Things to know The common control library is available today in all AWS Regions where AWS Audit Manager is offered. There is no additional cost for using the common control library. For more information, see AWS Audit Manager pricing.
This new capability streamlines the compliance and risk assessment process, reducing the workload for GRC teams and simplifying the way they can map enterprise controls into Audit Manager for evidence collection. To learn more, see the AWS Audit Manager User Guide.
The vibrant AWS community is made up of millions of builders worldwide. Within this global audience, there are technical enthusiasts who are going above and beyond to solve problems and generously share their learnings and best practices to empower others—the AWS Heroes. These inspirational leaders make significant contributions, and the AWS Heroes program is our way of recognizing and highlighting their impactful efforts.
Please join us in celebrating our newest group of AWS Heroes!
Arshad Zackeriya – Wellington, New Zealand
Community Hero Arshad Zackeriya is a Senior Engineer at Xero, specializing in empowering organizations to deliver software at high velocity. He is well-known in the community as “Zack,” and his expertise primarily centers around Amazon EKS and developer tools. Zack is also a public speaker, and serves as one of the co-organizers and leaders for the Wellington Chapter in the AWS User Group Aotearoa New Zealand. Additionally, he was an AWS New Voices Coach and was an AWS Community Builder for five consecutive years, earning recognition as a nominee for the AWS Community Builder of the Year for 2022 and 2023 in the APJ region.
Julia Furst Morgado – New York, USA
Container Hero Julia Furst Morgado is a Global Technologist on the Product Strategy team in the Office of the CTO at Veeam Software. She is committed to diversity and inclusion, and her passion lies in making Cloud Native technologies and DevOps best practices easier to understand by sharing her knowledge. Julia excels in evangelizing and creating engaging content focused on Amazon EKS, and presenting at major events about Amazon EKS Blueprints and Amazon EKS security. Additionally, she co-organizes the AWS Community Day New York, Kubernetes Community Days, and the AWS User Group Lisbon – Women in Tech chapter, fostering vibrant collaboration and learning opportunities.
Paloma Lataliza – Belo Horizonte, Brazil
Community Hero Paloma Lataliza is a Cloud Engineer with over six years of experience. She has a bachelor’s degree in Computer Science, specialized in Cloud Computing, is an enthusiast of container technologies and passionate about technology and sharing knowledge. Paloma is a leader of the AWS User Group Minas Gerais, and she is dedicated to mentoring women by providing a supportive network and offering them free classes to make tech more accessible. This is further demonstrated as the organizer of the AWSome Women Community Summit Brazil, and founder of the Mulheres na Nuvem Minas Gerais (Women in the Cloud Minas Gerais) project. Previously, she was an AWS Community Builder, producing technical content, speaking at Cloud and DevOps events, and mentoring those eager to deepen their technical skills.
Shaoyi Li – Shenzhen, China
Community Hero Shaoyi Li is a Lead Cloud Engineer focusing on cybersecurity and generative AI, advocating for cloud generative AI security and governance solutions to help the community build secure, compliant, and responsible generative AI applications. He is a regular speaker at AWS events, such as AWS Summits, AWS Community Days, and AWS User Group Meetups. Shaoyi also shares his insights into AWS technologies through various channels, including AWS case studies, AWS blogs, AWS WeChat channels, community.aws, and on his social networks.
Vishal Alhat – Pune, India
Community Hero Vishal Alhat is a Senior Software Engineer at Forcepoint, a leading cybersecurity company, where he leverages his 9+ years of experience to play a key role in cloud-based deployments. He focuses on cloud security and DevOps using AWS, implementing DevOps tools, AWS services, and best practices to automate deployments and ensure consistency across Forcepoint’s cloud infrastructure. Vishal is passionate about sharing his knowledge and was selected as the AWS Community Builder of the Year for the APJ region, which is a testament to his dedication. Furthermore, he is the AWS User Group Pune leader, and regularly speaks at conferences, meetups, AWS Community Days, and AWS Summits worldwide.
Learn More
Please visit the AWS Heroes website if you’d like to learn more about the AWS Heroes program or to connect with a Hero near you.
Join us in Philadelphia, Pennsylvania, on June 10–12, 2024, for AWS re:Inforce, a security learning conference where you can enhance your skills and confidence in cloud security, compliance, identity, and privacy. As an attendee, you will have access to hundreds of technical and non-technical sessions, an Expo featuring Amazon Web Services (AWS) experts and AWS Security Competency Partners, and keynote sessions led by industry leaders. AWS re:Inforce offers a comprehensive focus on six key areas, including Application Security.
The Application Security track helps you understand and implement best practices for securing your applications throughout the development lifecycle. This year, we are focusing on several key themes:
Building a culture of security – Learn how to define and influence organizational behavior to speed up application development, while reducing overall security risk through implementing best practices, training your internal teams, and defining ownership.
Security of the pipeline – Discover how to embed governance and guardrails to allow developer agility, while maintaining security across your continuous integration and delivery (CI/CD) pipelines.
Security in the pipeline – Explore tooling and automation to reduce the mean time of security reviews and embed continuous security into each stage of the development pipeline.
Supply chain security – Gain improved awareness of how risks are introduced by extension, track dependencies, and identify vulnerabilities used in your software.
Additionally, this year the Application Security track will have sessions focused on generative AI (gen AI), covering how to secure gen AI applications and use gen AI for development. Join these sessions to deepen your knowledge and up-level your skills, so that you can build modern applications that are robust, resilient, and secure.
Breakout sessions, chalk talks, lightning talks, and code talks
APS201 | Breakout session | Accelerate securely: The Generative AI Security Scoping Matrix As generative AI ignites business innovation, cybersecurity teams need to keep up with the accelerating domain. Security leaders are seeking tools and answers to help drive requirements around governance, compliance, legal, privacy, threat mitigations, resiliency, and more. This session introduces you to the Generative AI Security Scoping Matrix, which is designed to provide a common language and thought model for approaching generative AI security. Leave the session with a framework, techniques, and best practices that you can use to support responsible adoption of generative AI solutions designed to help your business move at an ever-increasing pace.
APS301 | Breakout session | Enhance AppSec: Generative AI integration in AWS testing This session presents an in-depth look at the AWS Security Testing program, emphasizing its scaling efforts to help ensure new products and services meet a high security bar pre-launch. With a focus on integrating generative AI into its testing framework, the program showcases how AWS anticipates and mitigates complex security threats to maintain cloud security. Learn about AWS’s proactive approaches to collaboration across teams and mitigating vulnerabilities, enriched by case studies that highlight the program’s flexibility and dedication to security excellence. Ideal for security experts and cloud architects, this session offers valuable insights into safeguarding cloud computing technologies.
APS302 | Breakout session | Building a secure MLOps pipeline, featuring PathAI DevOps and MLOps are both software development strategies that focus on collaboration between developers, operations, and data science teams. In this session, learn how to build modern, secure MLOps using AWS services and tools for infrastructure and network isolation, data protection, authentication and authorization, detective controls, and compliance. Discover how AWS customer PathAI, a leading digital pathology and AI company, uses seamless DevOps and MLOps strategies to run their AISight intelligent image management system and embedded AI products to support anatomic pathology labs and bio-pharma partners globally.
APS401 | Breakout session | Keeping your code secure Join this session to dive deep into how AWS implemented generative AI tooling in our developer workflows. Learn about the AWS approach to creating the underlying code scanning and remediation engines that AWS uses internally. Also, explore how AWS integrated these tools into the services we offer through reactive and proactive security features. Leave this session with a better understanding of how you can use AWS to secure code and how the code offered to you through AWS generative AI services is designed to be secure.
APS402 | Breakout session | Verifying code using automated reasoning In this session, AWS principal applied scientists discuss how they use automated reasoning to certify bug-free code mathematically and help secure underlying infrastructure. Explore how to use Kani, an AWS created open source engine that analyzes, verifies, and detects errors in safe and unsafe Rust code. Hear how AWS built and implemented Kani internally with examples taken from real-world AWS open source code. Leave this session with the tools you need to get started using this Rust verification engine for your own workloads.
APS232 | Chalk talk | Successful security team patterns It’s more common to hear what a security team does than to hear how the security team does it, or with whom the security team works rather than how it was designed to work. Organizational design is often demoted to a secondary consideration behind the goals of a security team, despite intentional design generally being what empowers, or hinders, security teams from achieving their goals. Security must work across the organization, not in isolation. This chalk talk focuses on designing effective security teams for organizations moving to the cloud, which necessitates outlining both what the security team works on and how it achieves that work.
APS331 | Chalk talk | Verifiable and auditable security inside the pipeline In this chalk talk, explore platform engineering best practices at AWS. AWS deploys more than 150 million times per year while maintaining 143 different compliance framework attestations and certifications. Internally, AWS has learned how to make security easier for builder teams. Learn key risks associated with operating pipelines at scale and Amazonian mechanisms to make security controls inside the pipeline verifiable and auditable so that you can shift compliance and auditing left into the pipeline.
APS233 | Chalk talk | Threat modeling your generative AI workload to evaluate security risk As the capabilities and possibilities of machine learning continue to expand with advances in generative AI, understanding the security risks introduced by these advances is essential for protecting your valuable AWS workloads. This chalk talk guides you through a practical threat modeling approach, empowering you to create a threat model for your own generative AI applications. Gain confidence to build your next generative AI workload securely on AWS with the help of threat modeling and leave with actionable steps you can take to get started.
APS321 | Lightning talk | Using generative AI to create more secure applications Generative AI revolutionizes application development by enhancing security and efficiency. This lightning talk explores how Amazon Q, your generative AI assistant, empowers you to build, troubleshoot, and transform applications securely. Discover how its capabilities streamline the process, allowing you to focus on innovation while ensuring robust security measures. Unlock the power of generative AI for helping build secure, cutting-edge applications.
APS341 | Code talk | Shifting left, securing right: Container supply chain security Supply chain security for containers helps ensure you can detect software security risks in third-party packages and remediate them during the container image build process. This prevents container images with vulnerabilities from being pushed to your container registry and causing potential harm to your production systems. In this code talk, learn how you can apply a shift-left approach to container image security testing in your deployment pipelines.
Hands-on sessions
APS373 | Workshop | Build a more secure generative AI chatbot with security guardrails Generative AI is an emerging technology that is disrupting multiple industries. An early generative AI use case is interactive chat in customer service applications. As users interact with generative AI chatbots, there are security risks, such as prompt injection and jailbreaking resulting from specially crafted inputs sent to large language models. In this workshop, learn how to build an AI chatbot using Amazon Bedrock and protect it using Guardrails for Amazon Bedrock. You must bring your laptop to participate.
APS351 | Builders’ session | Implement controls for the OWASP Top 10 for LLM applications In this builders’ session, learn how to implement security controls that address the OWASP Top 10 for LLM applications on AWS. Experts guide you through the use of AWS security tooling to provide practical insights and solutions to mitigate the most critical security risks outlined by OWASP. Discover technical options and choices you can make in cloud infrastructure and large-scale enterprise environments augmented by AWS generative AI technology. You must bring your laptop to participate.
APS271 | Workshop | Threat modeling for builders In this workshop, learn threat modeling core concepts and how to apply them through a series of group exercises. Key topics include threat modeling personas, key phases, data flow diagrams, STRIDE, and risk response strategies as well as the introduction of a “threat grammar rule” with an associated tool. In exercises, identify threats and mitigations through the lens of each threat modeling persona. Assemble in groups and walk through a case study, with AWS threat modeling experts on hand to guide you and provide feedback. You must bring your laptop to participate.
APS371 | Workshop | Integrating open source security tools with AWS code services AWS, open source, and partner tooling work together to accelerate your software development lifecycle. In this workshop, learn how to use the Automated Security Helper (ASH), an open source application security tool, to quickly integrate various security testing tools into your software build and deployment flows. AWS experts guide you through the process of security testing locally on your machines and within the AWS CodeCommit, AWS CodeBuild, and AWS CodePipeline services. In addition, discover how to identify potential security issues in your applications through static analysis, software composition analysis, and infrastructure-as-code testing. You must bring your laptop to participate.
This blog post highlighted some of the unique sessions in the Application Security track at the upcoming re:Inforce 2024 conference in Philadelphia. If these sessions pique your interest, register for re:Inforce 2024 to attend them, along with the numerous other Application Security sessions offered at the conference. For a comprehensive overview of sessions across all tracks, explore the AWS re:Inforce catalog preview.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Today, we are pleased to announce the general availability of the Terraform AWS Cloud Control (AWS CC) Provider, enabling our customers to take advantage of AWS innovations faster. AWS has been continually expanding its services to support virtually any cloud workload; supporting over 200 fully featured services and delighting customers through its rapid pace of innovation with over 3,400 significant new features in 2023. Our customers use Infrastructure as Code (IaC) tools such as HashiCorp Terraform among others as a best-practice to provision and manage these AWS features and services as part of their cloud infrastructure at scale. With the Terraform AWS CC Provider launch, AWS customers using Terraform as their IaC tool can now benefit from faster time-to-market by building cloud infrastructure with the latest AWS innovations that are typically available on the Terraform AWS CC Provider on the day of launch. For example, AWS customer Meta’s Oculus Studios was able to quickly leverage Amazon GameLift to support their game development. “AWS and Hashicorp have been great partners in helping Oculus Studios standardize how we deploy our GameLift infrastructure using industry best practices.” said Mick Afaneh, Meta’s Oculus Studios Central Technology.
The Terraform AWS CC Provider leverages AWS Cloud Control API to automatically generate support for hundreds of AWS resource types, such as Amazon EC2 instances and Amazon S3 buckets. Since the AWS CC provider is automatically generated, new features and services on AWS can be supported as soon as they are available on AWS Cloud Control API, addressing any coverage gaps in the existing Terraform AWS standard provider. This automated process allows the AWS CC provider to deliver new resources faster because it does not have to wait for the community to author schema and resource implementations for each new service. Today, the AWS CC provider supports 950+ AWS resources and data sources, with more support being added as AWS service teams continue to adopt the Cloud Control API standard.
As a Terraform practitioner, using the AWS CC Provider would feel familiar to the existing workflow. You can employ the configuration blocks shown below, while specifying your preferred region.
During Terraform plan or apply, the AWS CC Terraform provider interacts with AWS Cloud Control API to provision the resources by calling its consistent Create, Read, Update, Delete, or List (CRUD-L) APIs.
AWS Cloud Control API
AWS service teams own, publish, and maintain resources on the AWS CloudFormation Registry using a standardized resource model. This resource model uses uniform JSON schemas and provisioning logic that codifies the expected behavior and error handling associated with CRUD-L operations. This resource model enables AWS service teams to expose their service features in an easily discoverable, intuitive, and uniform format with standardized behavior. Launched in September 2021, AWS Cloud Control API exposes these resources through a set of five consistent CRUD-L operations without any additional work from service teams. Using Cloud Control API, developers can manage the lifecycle of hundreds of AWS and third-party resources with consistent resource-oriented API instead of using distinct service-specific APIs. Furthermore, Cloud Control API is up-to-date with the latest AWS resources as soon as they are available on the CloudFormation Registry, typically on the day of launch. You can read more on launch day requirement for Cloud Control API in this blog post. This enables AWS Partners such as HashiCorp to take advantage of consistent CRUD-L API operations and integrate Terraform with Cloud Control API just once, and then automatically access new AWS resources without additional integration work.
History and Evolution of the Terraform AWS CC Provider
The general availability of Terraform AWS CC Provider project is a culmination of 4+ years of collaboration between AWS and HashiCorp. Our teams partnered across the Product, Engineering, Partner, and Customer Support functions in influencing, shaping, and defining the customer experience leading up to the the technical preview announcement of the AWS CC provider in September 2021. At technical preview, the provider supported more than 300 resources. Since then, we have added an additional 600+ resources to the provider, bringing the total to 950+ supported resources at general availability.
Beyond just increasing resource coverage, we gathered additional signals from customer feedback during the technical preview and rolled out several improvements since September 2021. Customers care deeply about the user experience on the providers available on the Terraform registry. Customers sought practical examples in the form of sample HCL configurations for each resource that they could use to immediately test in order to confidently start using the provider. This prompted us to enrich the AWS CC provider with hundreds of practical examples for popular AWS CC provider resources in the Terraform registry. This was made possible by contributions of hundreds of Amazonians who became early adopters of the AWS CC provider. We also published a how-to guide for anyone interested in contributing to AWS CC provider examples. Furthermore, customers also wanted to minimize context switching by moving between Terraform and AWS service documentation on what each attribute of a resource signified and the type of values it needed as part of configuration. This empowered us to prioritize augmenting the provider with rich resource attribute description with information taken from AWS documentation. The documentation provides detailed information of how to use the attributes, enumerations of the accepted attribute values and other relevant information for dozens of popularly used AWS resources.
We also worked with HashiCorp on various bug fixes and feature enhancements for the AWS CC provider, as well as the upstream Cloud Control API dependencies. We improved handling for resources with complex nested attribute schemas, implemented various bug fixes to resolve unintended resource replacement, and refined provider behavior under various conditions to support the idempotency expected by Terraform practitioners. While this are not an exhaustive list of improvements, we continue to listen to customer feedback and iterate on improving the experience. We encourage you to try out the provider and share feedback on the AWS CC provider’s GitHub page.
Using the AWS CC Provider
Let’s take an example of a recently introduced service, Amazon Q Business, a fully managed, generative AI-powered assistant that you can configure to answer questions, provide summaries, generate content, and complete tasks based on your enterprise data. Amazon Q Business resources were available in AWS CC provider shortly after the April 30th 2024 launch announcement. In the following example, we’ll create a demo Amazon Q Business application and deploy the web experience.
As you see in this example, you can use both the AWS and AWS CC providers in the same configuration file. This allows you to easily incorporate new resources available in the AWS CC provider into your existing configuration with minimal changes. The AWS CC provider also accepts the same authentication method and provider-level features available in the AWS provider. This means you don’t have to add additional configuration in your CI/CD pipeline to start using the AWS CC provider. In addition, you can also add custom agent information inside the provider block as described in this documentation.
Things to know
The AWS CC provider is unique due to how it was developed and its dependencies with Cloud Control API and AWS resource model in the CloudFormation registry. As such, there are things that you should know before you start using the AWS CC provider.
The AWS CC provider is generated from the latest CloudFormation schemas, and will release weekly containing all new AWS services and enhancements added to Cloud Control API.
Certain resources available in the CloudFormation schema are not compatible with the AWS CC provider due to nuances in the schema implementation. You can find them on the GitHub issue list here. We are actively working to add these resources to the AWS CC provider.
The AWS CC provider requires Terraform CLI version 1.0.7 or higher.
Every AWS CC provider resource includes a top-level attribute `id` that acts as the resource identifier. If the CloudFormation resource schema also has a similarly named top-level attribute `id`, then that property is mapped to a new attribute named `<type>_id`. For example `web_experience_id` for `awscc_qbusiness_web_experience` resource.
If a resource attribute is not defined in the Terraform configuration, the AWS CC provider will honor the default values specified in the CloudFormation resource schema. If the resource schema does not include a default value, AWS CC provider will use attribute value stored in the Terraform state (taken from Cloud Control API GetResponse after resource was created).
In correlation to the default value behavior as stated above, when an attribute value is removed from the Terraform configuration (e.g. by commenting the attribute), the AWS CC provider will use the previous attribute value stored in the Terraform state. As such, no drift will be detected on the resource configuration when you run Terraform plan / apply.
The AWS CC provider data sources are either plural or singular with filters based on `id` attribute. Currently there is no native support for metadata sources such as `aws_region` or `aws_caller_identity`. You can continue to leverage the AWS provider data sources to complement your Terraform configuration.
If you want to dive deeper into AWS CC provider resource behavior, we encourage you to check the documentation here.
Conclusion
The AWS CC provider is now generally available and will be the fastest way for customers to access newly launched AWS features and services using Terraform. We will continue to add support for more resources, additional examples and enriching the schema descriptions. You can start using the AWS CC provider alongside your existing AWS standard provider. To learn more about the AWS CC provider, please check the HashiCorp announcement blog post. You can also follow the workshop on how to get started with AWS CC provider. If you are interested in contributing with practical examples for AWS CC provider resources, check out the how-to guide. For more questions or if you run into any issues with the new provider, don’t hesitate to submit your issue in the AWS CC provider GitHub repository.
Organizations are adopting Apache Kafka and Amazon Managed Streaming for Apache Kafka (Amazon MSK) to capture and analyze data in real time. Amazon MSK helps you build and run production applications on Apache Kafka without needing Kafka infrastructure management expertise or having to deal with the complex overhead associated with setting up and running Apache Kafka on your own. Since its inception, Apache Kafka has depended on Apache Zookeeper for storing and replicating the metadata of Kafka brokers and topics. Starting from Apache Kafka version 3.3, the Kafka community has adopted KRaft (Apache Kafka on Raft), a consensus protocol, to replace Kafka’s dependency on ZooKeeper for metadata management. In the future, the Apache Kafka community plans to remove the ZooKeeper mode entirely.
Today, we’re excited to launch support for KRaft on new clusters on Amazon MSK starting from version 3.7. In this post, we walk you through some details around how KRaft mode helps over the ZooKeeper approach. We also guide you through the process of creating MSK clusters with KRaft mode and how to connect your application to MSK clusters with KRaft mode.
Why was ZooKeeper replaced with KRaft mode
The traditional Kafka architecture relies on ZooKeeper as the authoritative source for cluster metadata. Read and write access to metadata in ZooKeeper is funneled through a single Kafka controller. For clusters with a large number of partitions, this architecture can create a bottleneck during scenarios such as an uncontrolled broker shutdown or controller failover, due to a single-controller approach.
KRaft mode addresses these limitations by managing metadata within the Kafka cluster itself. Instead of relying on a separate ZooKeeper cluster, KRaft mode stores and replicates the cluster metadata across multiple Kafka controller nodes, forming a metadata quorum. The KRaft controller nodes comprise a Raft quorum that manages the Kafka metadata log. By distributing the metadata management responsibilities across multiple controller nodes, KRaft mode improves recovery time for scenarios such as uncontrolled broker shutdown or controller failover. For more details on KRaft mode and its implementation, refer to the KIP-500: Replace ZooKeeper with a Self-Managed Metadata Quorum.
The following figure compares the three-node MSK cluster architecture with ZooKeeper vs. KRaft mode.
Amazon MSK with KRaft mode
Until now, Amazon MSK has supported Kafka clusters that rely on ZooKeeper for metadata management. One of the key benefits of Amazon MSK is that it handles the complexity of setting up and managing the ZooKeeper cluster at no additional cost. Many organizations use Amazon MSK to run large, business-critical streaming applications that require splitting their traffic across thousands of partitions. As the size of a Kafka cluster grows, the amount of metadata generated within the cluster increases proportionally to the number of partitions.
Two key properties govern the number of partitions a Kafka cluster can support: the per-node partition count limit and the cluster-wide partition limit. As mentioned earlier, the metadata management system based on ZooKeeper imposed a bottleneck on the cluster-wide partition limitation in Apache Kafka. However, with the introduction of KRaft mode in Amazon MSK starting with version 3.7, Amazon MSK now enables the creation of clusters with up to 60 brokers vs. the default quota of 30 brokers in ZooKeeper mode. Kafka’s scalability still fundamentally relies on expanding the cluster by adding more nodes to increase overall capacity. Consequently, the cluster-wide partition limit continues to define the upper bounds of scalability within the Kafka system, because it determines the maximum number of partitions that can be distributed across the available nodes. Amazon MSK manages the KRaft controller nodes at no additional cost.
Create and access an MSK cluster with KRaft mode
Complete the following steps to configure an MSK cluster with KRaft mode:
For Cluster creation method, select Custom create.
For Cluster name, enter a name.
For Cluster type¸ select Provisioned.
For Apache Kafka version, choose 3.7.x.
For Metadata mode, select KRaft.
Leave the other settings as default and choose Create cluster.
When the cluster creation is successful, you can navigate to the cluster and choose View client integration information, which will provide details about the cluster bootstrap servers.
Adapt your client applications and tools for accessing MSK clusters with KRaft mode
With the adoption of KRaft mode in Amazon MSK, customers using client applications and tools that connect to ZooKeeper to interact with MSK clusters will need to update them to reflect the removal of ZooKeeper from the architecture. Starting with version 1.0, Kafka introduced the ability for admin tools to use the bootstrap servers (brokers) as input parameters instead of a ZooKeeper connection string, and started deprecating ZooKeeper connection strings starting with version 2.5. This change was part of the efforts to decouple Kafka from ZooKeeper and pave the way for its eventual replacement with KRaft mode for metadata management. Instead of specifying the ZooKeeper connection string, clients will need to use the bootstrap.servers configuration option to connect directly to the Kafka brokers. The following table summarizes these changes.
.
With Zookeeper
With KRaft
Client and Services
bootstrap.servers=broker:<port> or zookeeper.connect=zookeeper:2181 (deprecated)
bootstrap.servers=broker:<port>
Admin Tools
kafka-topics --zookeeper zookeeper:2181 (deprecated) or kafka-topics —bootstrap-server broker:<port> … —command-config
In this post, we discussed how Amazon MSK has launched support for KRaft mode for metadata management. We also described how KRaft works and how it’s different from ZooKeeper.
Kalyan Janaki is Senior Big Data & Analytics Specialist with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS.
Tableau, a commonly used business intelligence (BI) application, can now propagate end-user identity down to Amazon Redshift. This has a triple benefit. It simplifies the sign-in experience for end users. It allows data owners to define access based on real end-user identity. It allows auditors to verify data access by users.
Trusted identity propagation allows applications that consume data (such as Tableau, Amazon QuickSight, Amazon Redshift Query Editor, Amazon EMR Studio, and others) to propagate the user’s identity and group memberships to the services that store and manage access to the data, such as Amazon Redshift, Amazon Athena, Amazon Simple Storage Service (Amazon S3), Amazon EMR, and others. Trusted identity propagation is a capability of IAM Identity Center that improves the sign-in experience across multiple analytics applications, simplifies data access management, and simplifies audit. End users benefit from single sign-on and do not have to specify the IAM roles they want to assume to connect to the system.
Before diving into more details, let’s agree on terminology.
And finally, when I write “downstream services”, I refer to the analytics engines and storage services that process, store, or manage access to your data: Amazon Redshift, Athena, S3, EMR, and others.
To understand the benefit of trusted identity propagation, let’s briefly talk about how data access was granted until today. When a user-facing application accesses data from a downstream service, either the upstream service uses generic credentials (such as “tableau_user“) or assumes an IAM role to authenticate against the downstream service. This is the source of two challenges.
First, it makes it difficult for the downstream service administrator to define access policies that are fine-tuned for the actual user making the request. As seen from the downstream service, all requests originate from that common user or IAM role. If Jeff and Jane are both mapped to the BusinessAnalytics IAM role, then it is not possible to give them different levels of access, for example, readonly and read-write. Furthermore, if Jeff is also in the Finance group, he needs to choose a role in which to operate; he cannot access data from both groups in the same session.
Secondly, the task of associating a data-access event to an end user involves some undifferentiated heavy lifting. If the request originates from an IAM role called BusinessAnalytics, then additional work is required to figure out which user was behind that action.
Well, this particular example might look very simple, but in real life, organizations have hundreds of users and thousands of groups to match to hundreds of datasets. There was an opportunity for us to Invent and Simplify.
Once configured, the new trusted identity propagation provides a technical mechanism for user-facing applications to access data on behalf of the actual user behind the keyboard. Knowing the actual user identity offers three main advantages.
First, it allows downstream service administrators to create and manage access policies based on actual user identities, the groups they belong to, or a combination of the two. Downstream service administrators can now assign access in terms of users, groups, and datasets. This is the way most of our customers naturally think about access to data—intermediate mappings to IAM roles are no longer necessary to achieve these patterns.
Second, auditors now have access to the original user identity in system logs and can verify that policies are implemented correctly and follow all requirements of the company or industry-level policies.
Third, users of BI applications can benefit from single sign-on between applications. Your end-users no longer need to understand your company’s AWS accounts and IAM roles. Instead, they can sign in to EMR Studio (for example) using their corporate single sign-on that they’re used to for so many other things they do at work.
How does trusted identity propagation work? Trusted identity propagation relies on standard mechanisms from our industry: OAuth2 and JWT. OAuth2 is an open standard for access delegation that allows users to grant third-party user-facing applications access to data on other services (downstream services) without exposing their credentials. JWT (JSON Web Token) is a compact, URL-safe means of representing identities and claims to be transferred between two parties. JWTs are signed, which means their integrity and authenticity can be verified.
How to configure trusted identity propagation Configuring trusted identity propagation requires setup in IAM Identity Center, at the user-facing application, and at the downstream service because each of these needs to be told to work with end-user identities. Although the particulars will be different for each application, they will all follow this pattern:
Configure an identity source in AWS IAM Identity Center. AWS recommends enabling automated provisioning if your identity provider supports it, as most do. Automated provisioning works through the SCIM synchronization standard to synchronize your directory users and groups into IAM Identity Center. You probably have configured this already if you currently use IAM Identity Center to federate your workforce into the AWS Management Console. This is a one-time configuration, and you don’t have to repeat this step for each user-facing application.
Configure your user-facing application to authenticate its users with your identity provider. For example, configure Tableau to use Okta.
Configure the connection between the user-facing application and the downstream service. For example, configure Tableau to access Amazon Redshift. In some cases, it requires using the ODBC or JDBC driver for Redshift.
Then comes the configuration specific to trusted identity propagation. For example, imagine your organization has developed a user-facing web application that authenticates the users with your identity provider, and that you want to access data in AWS on behalf of the current authenticated user. For this use case, you would create a trusted token issuer in IAM Identity Center. This powerful new construct gives you a way to map your application’s authenticated users to the users in your IAM Identity Center directory so that it can make use of trusted identity propagation. My colleague Becky wrote a blog post to show you how to develop such an application. This additional configuration is required only when using third-party applications, such as Tableau, or a customer-developed application, that authenticate outside of AWS. When using user-facing applications managed by AWS, such as Amazon QuickSight, no further setup is required.
Finally, downstream service administrators must configure the access policies based on the user identity and group memberships. The exact configuration varies from one downstream service to the other. If the application reads or writes data in Amazon S3, the data owner may use S3 Access Grants in the Amazon S3 console to grant access for users and groups to prefixes in Amazon S3. If the application makes queries to an Amazon Redshift data warehouse, the data owner must configure IAM Identity Center trusted connection in the Amazon Redshift console and match the audience claim (aud) from the identity provider.
Now that you have a high-level overview of the configuration, let’s dive into the most important part: the user experience.
The end-user experience Although the precise experience of the end user will obviously be different for different applications, in all cases, it will be simpler and more familiar to workforce users than before. The user interaction will begin with a redirect-based authentication single sign-on flow that takes the user to their identity provider, where they can sign in with credentials, multi-factor authentication, and so on.
Let’s look at the details of how an end user might interact with Okta and Tableau when trusted identity propagation has been configured.
Here is an illustration of the flow and the main interactions between systems and services.
Here’s how it goes.
1. As a user, I attempt to sign in to Tableau.
2. Tableau initiates a browser-based flow and redirects to the Okta sign-in page where I can enter my sign-in credentials. On successful authentication, Okta issues an authentication token (ID and access token) to Tableau.
3. Tableau initiates a JDBC connection with Amazon Redshift and includes the access token in the connection request. The Amazon Redshift JDBC driver makes a call to Amazon Redshift. Because your Amazon Redshift administrator enabled IAM Identity Center, Amazon Redshift forwards the access token to IAM Identity Center.
4. IAM Identity Center verifies and validates the access token and exchange the access token for an Identity Center issued token.
5. Amazon Redshift will resolve the Identity Center token to determine the corresponding Identity Center user and authorize access to the resource. Upon successful authorization, I can connect from Tableau to Amazon Redshift.
Once authenticated, I can start to use Tableau as usual.
And when I connect to Amazon Redshift Query Editor, I can observe the sys_query_history table to check who was the user who made the query. It correctly reports awsidc:<email address>, the Okta email address I used when I connected from Tableau.
With trusted identity propagation, you can now configure analytics systems to propagate the actual user identity, group membership, and attributes to AWS services such as Amazon Redshift, Amazon Athena, or Amazon S3. It simplifies the management of access policies on these services. It also allows auditors to verify your organization’s compliance posture to know the real identity of users accessing data.
Get started now and configure your Tableau integration with Amazon Redshift.
PS: Writing a blog post at AWS is always a team effort, even when you see only one name under the post title. In this case, I want to thank Eva Mineva, Laura Reith, and Roberto Migli for their much-appreciated help in understanding the many subtleties and technical details of trusted identity propagation.
Amazon Web Services (AWS) is pleased to announce the successful renewal of the United Kingdom Cyber Essentials Plus certification. The Cyber Essentials Plus certificate is valid for one year until March 22, 2025.
Cyber Essentials Plus is a UK Government–backed, industry-supported certification scheme intended to help organizations demonstrate controls against common cyber security threats. An independent third-party auditor certified by Information Assurance for Small and Medium Enterprises (IASME) completed the audit. The scope of our Cyber Essentials Plus certificate covers the AWS corporate network for the United Kingdom, Ireland, and Germany.
As always, we value your feedback and questions. Reach out to the AWS Compliance team through the Contact Us page. If you have feedback about this post, submit a comment in the Comments section below. To learn more about our other compliance and security programs, see AWS Compliance Programs.
Announced in preview form at re:Invent 2023, Amazon Elastic Compute Cloud (Amazon EC2) U7i instances with up to 32 TiB of DDR5 memory and 896 vCPUs are now available. Powered by custom fourth generation Intel Xeon Scalable Processors (Sapphire Rapids), these high memory instances are designed to support large, in-memory databases including SAP HANA, Oracle, and SQL Server. Here are the specs:
Instance Name
vCPUs
Memory (DDR5)
EBS Bandwidth
Network Bandwidth
u7i-12tb.224xlarge
896
12,288 GiB
60 Gbps
100 Gbps
u7in-16tb.224xlarge
896
16,384 GiB
100 Gbps
200 Gbps
u7in-24tb.224xlarge
896
24,576 GiB
100 Gbps
200 Gbps
u7in-32tb.224xlarge
896
32,768 GiB
100 Gbps
200 Gbps
The new instances deliver the best compute price performance for large in-memory workloads, and offer the highest memory and compute power of any SAP-certified virtual instance from a leading cloud provider.
Thanks to AWS Nitro System, all of the memory on the instance is available for use. For example, here’s the 32 TiB instance:
In comparison to the previous generation of EC2 High Memory instances, the U7i instances offer more than 135% of the compute performance, up to 115% more memory performance, and 2.5x the EBS bandwidth. This increased bandwidth allows you to transfer 30 TiB of data from EBS into memory in an hour or less, making data loads and cache refreshes faster than ever before. The instances also support ENA Express with 25 Gbps of bandwidth per flow, and provide an 85% improvement in P99.9 latency between instances.
Each U7i instance supports attachment of up to 128 General Purpose (gp2 and gp3) or Provisioned IOPS (io1 and io2 Block Express) EBS volumes. Each io2 Block Express volume can be as big as 64 TiB and can deliver up to 256K IOPS at up to 32 Gbps, making them a great match for U7i instances.
Things to Know Here are a couple of things that you should know about these new instances:
Regions – U7i instances are available in the US East (N. Virginia), US West (Oregon), and Asia Pacific (Seoul, Sydney) AWS Regions.
Operating Systems – Supported operating systems include Amazon Linux, Red Hat Enterprise Linux, SUSE Linux Enterprise Server, Ubuntu, and Windows Server.
Larger Instances – We are also working on offering even larger instance later this year with increased compute to meet our customer needs.
A full conference pass is $1,099. Register today with the code flashsale150 to receive a limited time $150 discount, while supplies last.
We’re counting down to AWS re:Inforce, our annual cloud security event! We are thrilled to invite security enthusiasts and builders to join us in Philadelphia, PA, from June 10–12 for an immersive two-and-a-half-day journey into cloud security learning. This year, we’ve expanded the event by half a day to give you more opportunities to delve into the latest security trends and technologies. At AWS re:Inforce, you’ll have the chance to explore the breadth of the Amazon Web Services (AWS) security landscape, learn how to operationalize security services, and enhance your skills and confidence in cloud security to improve your organization’s security posture. As an attendee, you will have access to over 250 sessions across multiple topic tracks, including data protection; identity and access management; threat detection and incident response; network and infrastructure security; generative AI; governance, risk, and compliance; and application security. Plus, get ready to be inspired by our lineup of customer speakers, who will share their firsthand experiences of innovating securely on AWS.
In this post, we’ll provide an overview of the key sessions that include lecture-style presentations featuring real-world use cases from our customers, as well as the interactive small-group sessions led by AWS experts that guide you through practical problems and solutions.
The threat detection and incident response track is designed to demonstrate how to detect and respond to security risks to help protect workloads at scale. AWS experts and customers will present key topics such as threat detection, vulnerability management, cloud security posture management, threat intelligence, operationalization of AWS security services, container security, effective security investigation, incident response best practices, and strengthening security through the use of generative AI and securing generative AI workloads.
Breakout sessions, chalk talks, and lightning talks
TDR201 | Breakout session | How NatWest uses AWS services to manage vulnerabilities at scale As organizations move to the cloud, rapid change is the new normal. Safeguarding against potential security threats demands continuous monitoring of cloud resources and code that are constantly evolving. In this session, NatWest shares best practices for monitoring their AWS environment for software and configuration vulnerabilities at scale using AWS security services like Amazon Inspector and AWS Security Hub. Learn how security teams can automate the identification and prioritization of critical security insights to manage alert fatigue and swiftly collaborate with application teams for remediation.
TDR301 | Breakout session | Developing an autonomous framework with Security Lake & Torc Robotics Security teams are increasingly seeking autonomy in their security operations. Amazon Security Lake is a powerful solution that allows organizations to centralize their security data across AWS accounts and Regions. In this session, learn how Security Lake simplifies centralizing and operationalizing security data. Then, hear from Torc Robotics, a leading autonomous trucking company, as they share their experience and best practices for using Security Lake to establish an autonomous security framework.
TDR302 | Breakout session | Detecting and responding to threats in generative AI workloads While generative AI is an emerging technology, many of the same services and concepts can be used for threat detection and incident response. In this session, learn how you can build out threat detection and incident response capabilities for a generative AI workload that uses Amazon Bedrock. Find out how to effectively monitor this workload using Amazon Bedrock, Amazon GuardDuty, and AWS Security Hub. The session also covers best practices for responding to and remediating security issues that may come up.
TDR303 | Breakout session | Innovations in AWS detection and response services In this session, learn about the latest advancements and recent AWS launches in the field of detection and response. This session focuses on use cases like threat detection, workload protection, automated and continual vulnerability management, centralized monitoring, continuous cloud security posture management, unified security data management, and discovery and protection of workloads and data. Through these use cases, gain a deeper understanding of how you can seamlessly integrate AWS detection and response services to help protect your workloads at scale, enhance your security posture, and streamline security operations across your entire AWS environment.
TDR304 | Breakout session | Explore cloud workload protection with GuardDuty, feat. Booking.com Monitoring your workloads at runtime allows you to detect unexpected activity sooner—before it escalates to broader business-impacting security issues. Amazon GuardDuty Runtime Monitoring offers fully managed threat detection that gives you end-to-end visibility across your AWS environment. GuardDuty’s unique detection capabilities are guided by AWS’s visibility into the cloud threat landscape. In this session, learn why AWS built the Runtime Monitoring feature and how it works. Also discover how Booking.com used GuardDuty for runtime protection, supporting their mission to make it easier for everyone to experience the world.
TDR305 | Breakout session | Cyber threat intelligence sharing on AWS Real-time, contextual, and comprehensive visibility into security issues is essential for resilience in any organization. In this session, join the Australian Cyber Security Centre (ACSC) as they present their Cyber Threat Intelligence Sharing (CTIS) program, built on AWS. With the aim to improve the cyber resilience of the Australian community and help make Australia the most secure place to connect online, the ACSC protects Australia from thousands of threats every day. Learn the technical fundamentals that can help you apply best practices for real-time, bidirectional sharing of threat intelligence across all sectors.
TDR331 | Chalk talk | Unlock OCSF: Turn raw logs into insights with generative AI So, you have security data stored using the Open Cybersecurity Schema Framework (OCSF)—now what? In this chalk talk, learn how to use AWS analytics tools to mine data stored using the OCSF and leverage generative AI to consume insights. Discover how services such as Amazon Athena, Amazon Q in QuickSight, and Amazon Bedrock can extract, process, and visualize security insights from OCSF data. Gain practical skills to identify trends, detect anomalies, and transform your OCSF data into actionable security intelligence that can help your organization respond more effectively to cybersecurity threats.
TDR332 | Chalk talk | Anatomy of a ransomware event targeting data within AWS Ransomware events can interrupt operations and cost governments, nonprofits, and businesses billions of dollars. Early detection and automated responses are important mechanisms that can help mitigate your organization’s exposure. In this chalk talk, learn about the anatomy of a ransomware event targeting data within AWS including detection, response, and recovery. Explore the AWS services and features that you can use to protect against ransomware events in your environment, and learn how you can investigate possible ransomware events if they occur.
TDR333 | Chalk talk | Implementing AWS security best practices: Insights and strategies Have you ever wondered if you are using AWS security services such as Amazon GuardDuty, AWS Security Hub, AWS WAF, and others to the best of their ability? Do you want to dive deep into common use cases to better operationalize AWS security services through insights developed via thousands of deployments? In this chalk talk, learn tips and tricks from AWS experts who have spent years talking to users and documenting guidance outlining AWS security services best practices.
TDR334 | Chalk talk | Unlock your security superpowers with generative AI Generative AI can accelerate and streamline the process of security analysis and response, enhancing the impact of your security operations team. Its unique ability to combine natural language processing with large existing knowledge bases and agent-based architectures that can interact with your data and systems makes it an ideal tool for augmenting security teams during and after an event. In this chalk talk, explore how generative AI will shape the future of the SOC and lead to new capabilities in incident response and cloud security posture management.
TDR431 | Chalk talk | Harnessing generative AI for investigation and remediation To help businesses move faster and deliver security outcomes, modern security teams need to identify opportunities to automate and simplify their workflows. One way of doing so is through generative AI. Join this chalk talk to learn how to identify use cases where generative AI can help with investigating, prioritizing, and remediating findings from Amazon GuardDuty, Amazon Inspector, and AWS Security Hub. Then find out how you can develop architectures from these use cases, implement them, and evaluate their effectiveness. The talk offers tenets for generative AI and security that can help you safely use generative AI to reduce cognitive load and increase focus on novel, high-value opportunities.
TDR432 | Chalk talk | New tactics and techniques for proactive threat detection This insightful chalk talk is led by the AWS Customer Incident Response Team (CIRT), the team responsible for swiftly responding to security events on the customer side of the AWS Shared Responsibility Model. Discover the latest trends in threat tactics and techniques observed by the CIRT, along with effective detection and mitigation strategies. Gain valuable insights into emerging threats and learn how to safeguard your organization’s AWS environment against evolving security risks.
TDR433 | Chalk talk | Incident response for multi-account and federated environments In this chalk talk, AWS security experts guide you through the lifecycle of a compromise involving federation and third-party identity providers. Learn how AWS detects unauthorized access and which approaches can help you respond to complex situations involving organizations with multiple accounts. Discover insights into how you can contain and recover from security events and discuss strong IAM policies, appropriately restrictive service control policies, and resource termination for security event containment. Also, learn how to build resiliency in an environment with IAM permission refinement, organizational strategy, detective controls, chain of custody, and IR break-glass models.
TDR227 | Lightning talk | How Razorpay scales threat detection using AWS Discover how Razorpay, a leading payment aggregator solution provider authorized by the Reserve Bank of India, efficiently manages millions of business transactions per minute through automated security operations using AWS security services. Join this lightning talk to explore how Razorpay’s security operations team uses AWS Security Hub, Amazon GuardDuty, and Amazon Inspector to monitor their critical workloads on AWS. Learn how they orchestrate complex workflows, automating responses to security events, and reduce the time from detection to remediation.
TDR321 | Lightning talk | Scaling incident response with AWS developer tools In incident response, speed matters. Responding to incidents at scale can be challenging as the number of resources in your AWS accounts increases. In this lightning talk, learn how to use SDKs and the AWS Command Line Interface (AWS CLI) to rapidly run commands across your estate so you can quickly retrieve data, identify issues, and resolve security-related problems.
TDR322 | Lightning talk | How Snap Inc. secures its services with Amazon GuardDuty In this lightning talk, discover how Snap Inc. established a secure multi-tenant compute platform on AWS and mitigated security challenges within shared Kubernetes clusters. Snap uses Amazon GuardDuty and the OSS tool Falco for runtime protection across build time, deployment time, and runtime phases. Explore Snap’s techniques for facilitating one-time cluster access through AWS IAM Identity Center. Find out how Snap has implemented isolation strategies between internal tenants using the Pod Security Standards (PSS) and network policies enforced by the Amazon VPC Container Network Interface (CNI) plugin.
TDR326 | Lightning talk | Streamlining security auditing with generative AI For identifying and responding to security-related events, collecting and analyzing logs is only the first step. Beyond this initial phase, you need to utilize tools and services to parse through logs, understand baseline behaviors, identify anomalies, and create automated responses based on the type of event. In this lightning talk, learn how to effectively parse security logs, identify anomalies, and receive response runbooks that you can implement within your environment.
Interactive sessions (builders’ sessions, code talks, and workshops)
TDR351 | Builders’ session | Accelerating incident remediation with IR playbooks & Amazon Detective In this builders’ session, learn how to investigate incidents more effectively and discover root cause with Amazon Detective. Amazon Detective provides finding-group summaries by using generative AI to automatically analyze finding groups. Insights in natural language then help you accelerate security investigations. Find out how you can create your own incident response playbooks and test them by handling multi-event security issues.
TDR352 | Builders’ session | How to automate containment and forensics for Amazon EC2 Automated Forensics Orchestrator for Amazon EC2 deploys a mechanism that uses AWS services to orchestrate and automate key digital forensics processes and activities for Amazon EC2 instances in the event of a potential security issue being detected. In this builders’ session, learn how to deploy and scale this self-service AWS solution. Explore the prerequisites, learn how to customize it for your environment, and experience forensic analysis on live artifacts to identify what potential unauthorized users could do in your environment.
TDR353 | Builders’ session | Preventing top misconfigurations associated with security events Have you ever wondered how you can prevent top misconfigurations that could lead to a security event? Join this builders’ session, where the AWS Customer Incident Response Team (CIRT) reviews some of the most commonly observed misconfigurations that can lead to security events. Then learn how to build mechanisms using AWS Security Hub and other AWS services that can help detect and prevent these issues.
TDR354 | Builders’ session | Insights in your inbox: Build email reporting with AWS Security Hub AWS Security Hub provides you with a comprehensive view of the security state of your AWS resources by collecting security data from across AWS accounts, AWS Regions, and AWS services. In this builders’ session, learn how to set up a customizable and automated summary email that distills security posture information, insights, and critical findings from Security Hub. Get hands-on with the Security Hub console and discover easy-to-implement code examples that you can use in your own organization to drive security improvements.
TDR355 | Builders’ session | Detecting ransomware and suspicious activity in Amazon RDS In this builders’ session, acquire skills that can help you detect and respond to threats targeting AWS databases. Using services such as AWS Cloud9 and AWS CloudFormation, simulate real-world intrusions on Amazon RDS and Amazon Aurora and use Amazon Athena to detect unauthorized activities. The session also covers strategies from the AWS Customer Incident Response Team (CIRT) for rapid incident response and configuring essential security settings to enhance your database defenses. The session provides practical experience in configuring audit logging and enabling termination protection to ensure robust database security measures.
TDR451 | Builders’ session | Create a generative AI runbook to resolve security findings Generative AI has the potential to accelerate and streamline security analysis, response, and recovery, enhancing the effectiveness of human engagement. In this builders’ session, learn how to use Amazon SageMaker notebooks and Amazon Bedrock to quickly resolve security findings in your AWS account. You rely on runbooks for the day-to-day operations, maintenance, and troubleshooting of AWS services. With generative AI, you can gain deeper insights into security findings and take the necessary actions to streamline security analysis and response.
TDR441 | Code talk | How to use generative AI to gain insights in Amazon Security Lake In this code talk, explore how you can use generative AI to gather enhanced security insights within Amazon Security Lake by integrating Amazon SageMaker Studio and Amazon Bedrock. Learn how AI-powered analytics can help rapidly identify and respond to security threats. By using large language models (LLMs) within Amazon Bedrock to process natural language queries and auto-generate SQL queries, you can expedite security investigations, focusing on relevant data sources within Security Lake. The talk includes a threat analysis exercise to demonstrate the effectiveness of LLMs in addressing various security queries. Learn how you can streamline security operations and gain actionable insights to strengthen your security posture and mitigate risks effectively within AWS environments.
TDR442 | Code talk | Security testing, the practical way Join this code talk for a practical demonstration of how to test security capabilities within AWS. The talk can help you evaluate and quantify your detection and response effectiveness against key metrics like mean time to detect and mean time to resolution. Explore testing techniques that use open source tools alongside AWS services such as Amazon GuardDuty and AWS WAF. Gain insights into testing your security configurations in your environment and uncover best practices tailored to your testing scenarios. This talk equips you with actionable strategies to enhance your security posture and establish robust defense mechanisms within your AWS environment.
TDR443 | Code talk | How to conduct incident response in your Amazon EKS environment Join this code talk to gain insights from both adversaries’ and defenders’ perspectives as AWS experts simulate a live security incident within an application across multiple Amazon EKS clusters, invoking an alert in Amazon GuardDuty. Witness the incident response process as experts demonstrate detection, containment, and recovery procedures in near real time. Through this immersive experience, learn how you can effectively respond to and recover from Amazon EKS–specific incidents, and gain valuable insights into incident handling within cloud environments. Don’t miss this opportunity to enhance your incident response capabilities and learn how to more effectively safeguard your AWS infrastructure.
TDR444 | Code talk | Identity forensics in the realm of short-term credentials AWS Security Token Service (AWS STS) is a common way for users to access AWS services and allows you to utilize role chaining for navigating AWS accounts. When investigating security incidents, understanding the history and potential impact is crucial. Examining a single session is often insufficient because the initial abused credential may be different than the one that precipitated the investigation, and other tokens might be generated. Also, a single session investigation may not encompass all permissions that the adversary controls, due to trust relationships between the roles. In this code talk, learn how you can construct identity forensics capabilities using Amazon Detective and create a custom graph database using Amazon Neptune.
TDR371-R | Workshop | Threat detection and response on AWS Join AWS experts for an immersive threat detection and response workshop using Amazon GuardDuty, Amazon Inspector, AWS Security Hub, and Amazon Detective. This workshop simulates security events for different types of resources and behaviors and illustrates both manual and automated responses with AWS Lambda. Dive in and learn how to improve your security posture by operationalizing threat detection and response on AWS.
TDR372-R | Workshop | Container threat detection and response with AWS security services Join AWS experts for an immersive container security workshop using AWS threat detection and response services. This workshop simulates scenarios and security events that may arise while using Amazon ECS and Amazon EKS. The workshop also demonstrates how to use different AWS security services to detect and respond to potential security threats, as well as suggesting how you can improve your security practices. Dive in and learn how to improve your security posture when running workloads on AWS container orchestration services.
TDR373-R | Workshop | Vulnerability management with Amazon Inspector and Jenkins Join AWS experts for an immersive vulnerability management workshop using Amazon Inspector and Jenkins for continuous integration and continuous delivery (CI/CD). This workshop takes you through approaches to vulnerability management with Amazon Inspector for EC2 instances, container images residing in Amazon ECR and within CI/CD tools, and AWS Lambda functions. Explore the integration of Amazon Inspector with Jenkins, and learn how to operationalize vulnerability management on AWS.
Browse the full re:Inforce catalog to learn more about sessions in other tracks, plus gamified learning, innovation sessions, partner sessions, and labs.
Our comprehensive track content is designed to help arm you with the knowledge and skills needed to securely manage your workloads and applications on AWS. Don’t miss out on the opportunity to stay updated with the latest best practices in threat detection and incident response. Join us in Philadelphia for re:Inforce 2024 by registering today. We can’t wait to welcome you!
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Last week, Dr. Matt Wood, VP for AI Products at Amazon Web Services (AWS), delivered the keynote at the AWS Summit Los Angeles. Matt and guest speakers shared the latest advancements in generative artificial intelligence (generative AI), developer tooling, and foundational infrastructure, showcasing how they come together to change what’s possible for builders. You can watch the full keynote on YouTube.
Announcements during the LA Summit included two new Amazon Q courses as part of Amazon’s AI Ready initiative to provide free AI skills training to 2 million people globally by 2025. The courses are part of the Amazon Q learning plan. But that’s not all that happened last week.
Last week’s launches Here are some launches that got my attention:
LlamaIndex support for Amazon Neptune — You can now build Graph Retrieval Augmented Generation (GraphRAG) applications by combining knowledge graphs stored in Amazon Neptune and LlamaIndex, a popular open source framework for building applications with large language models (LLMs) such as those available in Amazon Bedrock. To learn more, check the LlamaIndex documentation for Amazon Neptune Graph Store.
AWS CloudFormation launches a new parameter called DeletionMode for the DeleteStack API — You can use the AWS CloudFormation DeleteStack API to delete your stacks and stack resources. However, certain stack resources can prevent the DeleteStack API from successfully completing, for example, when you attempt to delete non-empty Amazon Simple Storage Service (Amazon S3) buckets. The DeleteStack API can enter into the DELETE_FAILED state in such scenarios. With this launch, you can now pass FORCE_DELETE_STACK value to the new DeletionMode parameter and delete such stacks. To learn more, check the DeleteStack API documentation.
Mistral Small now available in Amazon Bedrock — The Mistral Small foundation model (FM) from Mistral AI is now generally available in Amazon Bedrock. This a fast-follow to our recent announcements of Mistral 7B and Mixtral 8x7B in March, and Mistral Large in April. Mistral Small, developed by Mistral AI, is a highly efficient large language model (LLM) optimized for high-volume, low-latency language-based tasks. To learn more, check Esra’s post.
New Amazon CloudFront edge location in Cairo, Egypt — The new AWS edge location brings the full suite of benefits provided by Amazon CloudFront, a secure, highly distributed, and scalable content delivery network (CDN) that delivers static and dynamic content, APIs, and live and on-demand video with low latency and high performance. Customers in Egypt can expect up to 30 percent improvement in latency, on average, for data delivered through the new edge location. To learn more about AWS edge locations, visit CloudFront edge locations.
Amazon OpenSearch Service zero-ETL integration with Amazon S3 — This Amazon OpenSearch Service integration offers a new efficient way to query operational logs in Amazon S3 data lakes, eliminating the need to switch between tools to analyze data. You can get started by installing out-of-the-box dashboards for AWS log types such as Amazon VPC Flow Logs, AWS WAF Logs, and Elastic Load Balancing (ELB). To learn more, check out the Amazon OpenSearch Service Integrations page and the Amazon OpenSearch Service Developer Guide.
Upcoming AWS events Check your calendars and sign up for these AWS events:
AWS Summits — It’s AWS Summit season! Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Dubai (May 29), Bangkok (May 30), Stockholm (June 4), Madrid (June 5), and Washington, DC (June 26–27).
AWS re:Inforce — Join us for AWS re:Inforce (June 10–12) in Philadelphia, PA. AWS re:Inforce is a learning conference focused on AWS security solutions, cloud security, compliance, and identity. Connect with the AWS teams that build the security tools and meet AWS customers to learn about their security journeys.
AWS Community Days — Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Midwest | Columbus (June 13), Sri Lanka (June 27), Cameroon (July 13), New Zealand (August 15), Nigeria (August 24), and New York (August 28).
Today, I am happy to announce that the Mistral Small foundation model (FM) from Mistral AI is now generally available in Amazon Bedrock. This a fast-follow to our recent announcements of Mistral 7B and Mixtral 8x7B in March, and Mistral Large in April. You can now access four high-performing models from Mistral AI in Amazon Bedrock including Mistral Small, Mistral Large, Mistral 7B, and Mixtral 8x7B, further expanding model choice.
Mistral Small, developed by Mistral AI, is a highly efficient large language model (LLM) optimized for high-volume, low-latency language-based tasks. Mistral Small is perfectly suited for straightforward tasks that can be performed in bulk, such as classification, customer support, or text generation. It provides outstanding performance at a cost-effective price point.
Some key features of Mistral Small you need to know about:
Retrieval-Augmented Generation (RAG) specialization – Mistral Small ensures that important information is retained even in long context windows, which can extend up to 32K tokens.
Coding proficiency – Mistral Small excels in code generation, review, and commenting, supporting major coding languages.
Multilingual capability – Mistral Small delivers top-tier performance in French, German, Spanish, and Italian, in addition to English. It also supports dozens of other languages.
Getting started with Mistral Small I first need access to the model to get started with Mistral Small. I go to the Amazon Bedrock console, choose Model access, and then choose Manage model access. I expand the Mistral AI section, choose Mistral Small, and then choose Save changes.
I now have model access to Mistral Small, and I can start using it in Amazon Bedrock. I refresh the Base models table to view the current status.
I use the following template to build a prompt for the model to get sub-optimal outputs:
<s>[INST] Instruction [/INST]
Note that <s> is a special token for beginning of string (BOS) while [INST] and [/INST] are regular strings.
I try the following prompt to see a classification example:
Prompt:
<s>[INST] Classify the following email to determine if it is spam or not. Only respond with the exact words "Spam" or "Not spam".
 🎉 Limited time offer! Buy 2, Get 1 Free! Offer ends today! Don't miss out the CHANCE TO SAVE, please click on the link below: https://bit.ly/buy-2-get-1-free [/INST]
Mistral 7B, Mixtral 8x7B, and Mistral Large can all correctly classify this email as “Spam.” Mistral Small is also able to classify this accurately, just as the larger models can. I also try several similar tasks, such as generating a Bash script from a text prompt and generating a recipe to prepare yoghurt, and get good results. For this reason, Mistral Small is the most cost-effective and efficient option of the Mistral AI models in Amazon Bedrock for such tasks.
Mistral Small excels in multilingual tasks. Along with English, it delivers superior performance in French, German, Spanish, and Italian. I test the model’s understanding of the German language by asking it to give me two sentences about sustainability:
Prompt:
<s>[INST] Geben Sie mir zwei Sätze zum Thema Nachhaltigkeit. [/INST]
Output:
1. Nachhaltigkeit bedeutet, die Bedürfnisse der heutigen Generation zu befriedigen, ohne die Möglichkeiten künftiger Generationen zu gefährden.
 2. Ein nachhaltiger Lebensstil umfasst den bewussten Umgang mit Ressourcen, wie Wasser, Energie und Rohstoffen, sowie den Schutz von Umwelt und Klima.
 Diese Sätze sollten Ihnen einen guten Überblick über das Thema Nachhaltigkeit geben.
Programmatically interact with Mistral Small I can use AWS Command Line Interface (AWS CLI) and AWS Software Development Kit (SDK) to programmatically interact with Mistral Small using Amazon Bedrock APIs. I use the following code in Python, which interacts with Amazon Bedrock Runtime APIs with AWS SDK, asking, “What is the color of the sky?”:
Amazon OpenSearch Ingestion is a fully managed serverless pipeline that allows you to ingest, filter, transform, enrich, and route data to an Amazon OpenSearch Service domain or Amazon OpenSearch Serverless collection. OpenSearch Ingestion is capable of ingesting data from a wide variety of sources and has a rich ecosystem of built-in processors to take care of your most complex data transformation needs.
In this post, we walk you through the new UI enhancements and blueprint discovery features that are now available with OpenSearch Ingestion for a richer user experience.
Blueprint discovery
Rather than create a pipeline definition from scratch, you can use configuration blueprints, which are preconfigured templates for common ingestion scenarios such as trace analytics or Apache logs. Configuration blueprints help you provision pipelines without having to author a configuration from scratch.
With the older interface, you had to scroll through a dropdown menu of all the available blueprints and couldn’t filter the blueprints using search. OpenSearch Ingestion now offers a new UI that enables searching for blueprints using full-text search on the AWS Management Console, helping you discover all the sources that you can ingest data from into OpenSearch Service.
When you create a new pipeline on the OpenSearch Service console, you’re presented with a new catalog page. You now have a top-down view of all the sources and sinks supported by OpenSearch Ingestion. The blueprints are listed as tiles with icons and are grouped together thematically.
The new catalog has a navigation menu that lists the blueprints, grouped by use case or the service that you want to ingest data from. You can either search for a blueprint or choose the shortcuts in the navigation pane. For example, if you’re building a pipeline to perform a zero-ETL integration with Amazon DynamoDB, you can either search for DynamoDB, choose ZeroETL under Use case in the navigation pane, or choose DynamoDB under Service.
Customized getting started guide
After you choose your blueprint, you’re directed to the Pipeline settings and configuration page. The new UI for blueprints offers a customized getting started guide for each source, detailing key steps in setting up a successful end-to-end integration. The guide on this page will change depending on the blueprint you chose for your pipeline.
The pipeline configuration is pre-filled with a template that you can modify with your specific sources, AWS Identity and Access Management (IAM) roles, and sinks. For example, if you chose the Zero-ETL with DocumentDB blueprint, the getting started guide will provide information on setting up a DocumentDB collection, permissions, and destination.
Support for JSON pipeline configuration
As part of the visual overhaul, OpenSearch Ingestion now offers support for specifying the pipeline configuration in JSON format on the console in addition to the existing YAML support. You can now view the configurations in JSON format in addition to the YAML format and edit them in place.
Although YAML is more human readable, it’s whitespace sensitive and is often challenging when copy/pasting from text editors. The JSON pipeline configuration allows you to confidently copy and paste configurations from your text or code editors without having to worry about formatting errors due to inconsistent whitespace. In addition, you can now make any edits in place with JSON configuration and the changes will be propagated to the YAML automatically.
Availability and pricing
These features are available in all commercial AWS Regions where OpenSearch Ingestion is currently available.
Ingestion-OCUs remain at the same price of $0.24 cents per hour. OCUs are billed on an hourly basis with per-minute granularity. You can control the costs OCUs incur by configuring maximum OCUs that a pipeline is allowed to scale.
Conclusion
In this post, we showed you the new blueprint discovery and other UI enhancements for OpenSearch Ingestion. Refer to Amazon OpenSearch Ingestion to learn about other capabilities provided by OpenSearch Ingestion to build scalable pipelines for your OpenSearch data ingestion needs.
About the author
Jagadish Kumar (Jag) is a Senior Specialist Solutions Architect at AWS focused on Amazon OpenSearch Service. He is deeply passionate about Data Architecture and helps customers build analytics solutions at scale on AWS.
Sam Selvan is a Principal Specialist Solution Architect with Amazon OpenSearch Service.
Amazon Simple Email Service (SES) is a cloud-based email sending service provided by Amazon Web Services (AWS), handling both inbound and outbound email traffic for your applications. It allows users to send and receive email using SES’s reliable and cost-effective infrastructure without having to provision email servers yourself.
Managing multiple email workloads at scale can be a daunting task for organizations. From handling high volumes of emails to routing them efficiently, and ensuring uniform compliance with regulations, the challenges can be overwhelming. Managing different types of outbound emails, whether one-to-one user email, transactional or marketing emails generated from applications, also becomes challenging due to increasing concerns of security and compliance requirements. To help customers tackle these pain points, Amazon Web Services (AWS) has introduced a new feature to streamline inbound and outbound email management: SES Mail Manager.
The challenge: Managing different email flows efficiently with compliance and security in place
Efficiently routing and processing emails to the appropriate teams or systems while ensuring proper filtering, security, and compliance is a complex undertaking. Meanwhile, outbound email flows have become increasing complex. Besides emails being sent between users, more and more emails are generated from different types of applications. On top of that, keeping up security and compliance requirements is an ongoing task for all IT administrators and CISOs. Maintaining email integrations with existing business applications, providing scalability and redundancy to accommodate spikes, and facilitating long-term archiving and retrieval further compound the difficulties. Without a robust and scalable solution, organizations struggle to manage email communications effectively, hindering productivity and exposing themselves to risks.
Solution: Amazon SES Mail Manager
Amazon SES Mail Manager is a comprehensive solution with powerful set of email gateway features that strengthens your organization’s email infrastructure. It simplifies email workflow management and streamlines compliance control, while integrating seamlessly with your existing systems. Mail Manager consolidates all incoming and outgoing email through a single control point. This allows you to apply unified tools, rules, and delivery behaviors across your entire email flow. The centralized approach improves reliability, security, and flexibility.
Some key capabilities include connecting different business applications, automating inbound email processing, managing outgoing emails, enhancing compliance through email archiving, and efficiently controlling overall email traffic. It provides a centralized hub to optimize email infrastructure, simplify processes, ensure compliance, and maintain a high degree of reliability and security.
Mail Manager features
Ingress Endpoints: Customizable SMTP endpoints for receiving emails
Ingress endpoint is a key infrastructure component that utilizes filtering polices and rules that you can configure to determine which emails should be allowed into your organization and which ones should be rejected.
Amazon SES currently offers a way to receive incoming emails from the internet using its SMTP interface called SES Inbound. This provided a shared, regional SMTP endpoint that all SES customers could use to accept emails. Improved upon this, Mail Manager introduces a more flexible and powerful approach with different types of ingress endpoints to handling inbound email with Amazon SES.
Mail Manager now offers two options for customers: Open Ingress Endpoint, Authenticated Ingress Endpoint.
Open Ingress Endpoints allows you to create unique, customizable SMTP endpoints that give you control to accept or reject email messages tailored to your specific needs. Open Ingress Points do not require domain verification to receive inbound emails. Simply point your domain’s MX record to the newly created Ingress Endpoint, and it will start receiving emails for that domain.
Authenticated Ingress Endpoints in Mail Manager also enables a new capability – allowing SES to accept emails from trusted external SMTP servers for further processing. Users can create a Traffic Policy to configure trusted external SMTP servers with either type of Ingress Endpoints. What’s different about Authenticated Ingress Endpoints is, users need to use SMTP Authorization to send messages. Once provisioned, you obtain credentials to connect your existing email infrastructure to the Authenticated Ingress Endpoint as an outgoing email server.
For step-by-step guide on how to create this, refer to documentation.
Traffic policies & policy statements
Traffic Policies enable fine-grained control over accepting or rejecting inbound email. A traffic policy is a container for policy statements that you assign to an ingress endpoint, so that it can sort the incoming mail by allowing or blocking specific types of email when the conditions of the policy statements are met. You have the option to set a maximum message size so that any email with a size greater, will immediately be discarded—this acts as a “first pass” filter when set. Next, you set either Allow or Deny as the default action that’s taken for email that falls outside of the conditions of your policy statements. This is the “catch all” action for the traffic policy.
Policy statements are also created with either an allow or block action that is taken when the statements’ conditions are met. You build the conditions by selecting an email protocol and a conditional operator for a value you enter that must be matched by the incoming message before the policy statement will allow or block it. The three conditions available in the policy statement are Recipient address, Sender IP range and TLS protocol version. Each policy statement can have multiple conditions.
Rule Sets & rules
Taking Control with Rule Sets: After traffic policies permit certain messages into Mail Manager, customers use rule sets to apply custom processing logic for routing, optional functions, archiving, and delivery. You can add multiple Rules within a Rule Set. You can specify the order in which Rules within a Rule Set are evaluated, as well as the order of Actions within each Rule. Each Rule consists of: Conditions: Criteria that an email must match for the Rule to be applied. Exceptions: Criteria that, if matched, will exempt the email from the Rule. Actions: The operations to be performed on emails that meet the Rule’s Conditions and don’t match any Exceptions.
Recipient-Oriented Processing:
Mail Manager processes emails in a recipient-oriented manner, meaning rules are applied separately for each recipient. In traditional email gateways, rules are typically applied at the message level, affecting all recipients uniformly. For instance, if a rule in a traditional gateway adds a header for emails addressed to [email protected], all recipients of that email will see the header. This can lead to unintended side effects where actions meant for one recipient affect others. With Mail Manager, only emails to [email protected] will have the header, ensuring rules are specific to each recipient.
Additionally, Mail Manager allows rules to be applied to all recipients when needed, such as using the Subject header as a rule condition. This flexibility provides greater precision and control in email processing, allowing rules administrators to tailor the application of rules to meet specific requirements for individual recipients or for the entire email.
By enabling both recipient-oriented and message-oriented approaches, it enhances privacy, compliance, and security by preventing unintended data exposure and ensuring actions are applied only where intended.
Flexible Conditions and Actions: Mail Manager’s Rule Sets offer a powerful expression language for defining conditions based on various email properties, such as recipient address, TLS version, source IP, subject header, and more. Additionally, Rule Sets support a wide range of Actions, including:
With these capabilities, Rule Sets enable you to build sophisticated, automated email processing workflows tailored to your organization’s needs.
SMTP Relay
Mail Manager’s SMTP Relay functionality allows you to integrate your inbound email processing workflows with external email infrastructure, such as on-premises Microsoft Exchange servers or third-party email gateways. Mail Manager’s SMTP Relay functionality allows you to integrate your email flows with appropriate servers based on predefined criteria, optimizing the journey of every email.
How SMTP Relay Works:
Define an SMTP Relay – First, you create an SMTP Relay resource within Mail Manager, specifying the details of the external SMTP server you want to relay emails to, such as the server hostname, port, and authentication credentials (if required).
Create a Rule with the SMTP Relay Action Next, within a Rule Set, you create a Rule that includes the “SMTP Relay” action, selecting the SMTP Relay resource you defined earlier.
Configure the Rule Conditions You then set the conditions for this Rule, determining which incoming emails should be relayed to the external SMTP server. For example, you could set a condition to relay all email destined for a specific domain (e.g., “@gmail.com”).
Assign the Rule Set to an Ingress Endpoint Finally, you assign the Rule Set containing this Rule to one or more Ingress Endpoints.
When an email matching the Rule’s conditions is received by the Ingress Endpoint, Mail Manager will automatically relay that email to the external SMTP server specified in the SMTP Relay resource.
Use Cases for SMTP Relay:
Processing layer for incoming emails: Relay incoming emails from Mail Manager after rules engine processing to your email server whether it’s on-premises or cloud email system.
Supporting hybrid and migration: In hybrid email environments where some mailboxes are hosted on-premises and others are in the cloud (e.g., Microsoft 365 or Google Workspace), SMTP relay allows for seamless communication between the two environments. During email migration projects, SMTP relay can be used to temporarily route emails between the old and new email platforms, ensuring that no messages are lost during the transition period.
Mailbox resilience: By terminating MX at Mail Manager, and then configuring rules for delivery to 1 or more mailbox providers, you can manage resilient mailbox delivery if your primary mailbox provider is impaired. No DNS propagation delays, just change the delivery rule and instantly fall into your other system.
Enforcement layer: Integrate Mail Manager with third-party email services or gateways by relaying emails to their SMTP endpoints, leveraging their capabilities to enforce additional policies or security measures while maintaining control with Mail Manager.
Inter-Server Communication: SMTP relay facilitates communication between different internal email servers or systems within the organization’s network, ensuring seamless delivery of emails across various domains or platforms.
Load balancing and redundancy: Distribute email traffic across multiple servers or gateways to optimize performance and resource utilization, ensuring high availability and fault tolerance.
With SMTP Relay, Mail Manager acts as a flexible email processing layer, allowing you to incorporate its powerful capabilities while maintaining and extending your current email infrastructure investments.
Email Archiving
As organizations face increasing regulatory and compliance requirements around email retention, Mail Manager provides a robust email archiving solution. The archiving feature allows you to securely store and easily search through your email data, ensuring you meet your archiving obligations.
How Email Archiving Works:
You create an archive resource within Mail Manager, specifying the desired retention period for your archived emails.
Create a Rule with the archive action within a Rule Set. Create a Rule that includes the “Archive” action, selecting the Archive resource you defined earlier.
You then set the conditions for this Rule, determining which incoming emails should be archived. For example, you could archive all emails sent to a specific department’s email alias.
Finally, you assign the Rule Set containing this archiving Rule to one or more Ingress Endpoints.
Now, when an email matching the Rule’s conditions is received by the Ingress Endpoint, Mail Manager will automatically archive a verbatim copy of that email to the designated Archive resource.
Mail Manager’s archiving capabilities offer several advantages for organizations:
Archiving stores email data in a secure, durable, and searchable archive, meeting regulatory requirements for email retention and enabling efficient audits.
Utilize powerful search filters to locate specific emails within your archive, and export search results for further analysis or legal purposes.
Reduce the storage burden on your mail servers by archiving emails to Mail Manager’s scalable and cost-effective storage solution.
Set customizable retention periods for your archives, ensuring important email data is preserved for as long as needed.
By integrating email archiving into your Mail Manager workflows, you can maintain a comprehensive, searchable, and compliant email archive without the hassle of managing additional infrastructure.
Email Add-ons
Mail Manager offers a suite of specialized security tools, called Email Add-ons, that allow you to enhance your email security posture and tailor your inbound email workflows to your specific needs. Add-ons can be used as conditions within Traffic Policies to control which emails are allowed into your Ingress Endpoints, or as conditions within Rule Sets to determine the actions taken on specific email types. These Add-ons are certified security intelligence and enforcement solutions from vetted providers, ready to be integrated directly into your Mail Manager environment (e.g., Spamhaus Domain Block List, Abusix Mail Intelligence, Trend Micro Virus Scanning).
Email Add-Ons provide a flexible and modular approach to email security, enabling you to select and combine the solutions that best fit your unique use cases. Instead of investing in a monolithic product that may not fully align with your requirements, you can choose from a range of Add-ons and pay only for the capabilities you need, on a metered-price basis. Once you’ve subscribed to an Email Add-on from the Mail Manager console, you can seamlessly incorporate it into your email workflows.
Email Add-ons extend Mail Manager’s core threat intelligence and security enforcement features on a per-workload basis, ensuring you have the right level of protection without over-provisioning resources. Within the Mail Manager console, you can explore detailed product descriptions, key benefits, and pricing information for each Add-on, empowering you to make informed decisions.
Key benefits of Add-ons:
Immediate use: no separate setup/integration work required.
Cost effective: pay for only what is needed and consumed, turn on and off as required
Granular deployment via individual traffic policy or rule action
Conclusion:
Amazon SES Mail Manager introduces advanced email routing and archiving features, providing significant benefits to customers. With customizable SMTP endpoints and recipient-oriented rule processing, customers gain precise control over email traffic, ensuring that rules are applied specifically to each recipient. The enhanced traffic policies improve email security and compliance, while the robust SMTP relay functionality seamlessly integrates with existing systems, ensuring efficient email routing and processing. Mail Manager’s archiving capabilities help meet regulatory requirements and simplify data management. Overall, Mail Manager streamlines email operations, optimizes infrastructure, and enhances reliability, security, and compliance, offering a powerful solution for managing complex email workflows.
About the Authors:
Jessica Fan is a Senior Product Manager at AWS, striving to improve the experience for Amazon SES customers. Outside of work, she enjoys long distance running, biking and bouldering.
Vinay Ujjini is an Amazon Pinpoint and Amazon Simple Email Service Worldwide Principal Specialist Solutions Architect at AWS. He has been solving customer’s omni-channel challenges for over 15 years. He is an avid sports enthusiast and in his spare time, enjoys playing tennis & cricket.
We continue to expand the scope of our assurance programs at Amazon Web Services (AWS) and are pleased to announce that the Spring 2024 System and Organization Controls (SOC) 1, 2, and 3 reports are now available. The reports cover the 12-month period from April 1, 2023 to March 31, 2024, so that customers have a full year of assurance from each report. These reports demonstrate our continuous commitment to adhere to the heightened expectations for cloud service providers.
The Spring 2024 SOC reports include an additional six services in scope, for a total of 177 services in scope. For up-to-date information, including when additional services are added, visit the AWS Services in Scope by Compliance Program webpage and choose SOC.
The six additional services in scope for the Spring 2024 SOC reports are:
AWS strives to continuously bring services into scope of its compliance programs to help you meet your architectural and regulatory needs. Please reach out to your AWS account team if you have questions or feedback about SOC compliance.
To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.
If you have feedback about this post, submit comments in the Comments section below.
During this special onboarding, we added two additional AWS Regions (Israel (Tel Aviv)) and Canada West (Calgary)) and three additional AWS services to the scope since the last certification issued on Nov 22, 2023. The following are the three additional services:
For a full list of AWS services that are certified under ISO and CSA Star, see the AWS ISO and CSA STAR Certified page. Customers can also access the certifications in the AWS Management Console through AWS Artifact.
If you have feedback about this post, submit comments in the Comments section below.
Want more AWS Security how-to content, news, and feature announcements? Follow us on X.
AWS Summit season is in full swing around the world, with last week’s events in Bengaluru, Berlin, and Seoul, where my blog colleague Channy delivered one of the keynotes.
Last week’s launches Here are some launches that got my attention:
Amazon S3 will no longer charge for several HTTP error codes – A customer reported how he was charged for Amazon S3 API requests he didn’t initiate and which resulted in AccessDenied errors. The Amazon Simple Storage Service (Amazon S3) service team updated the service to not charge such API requests anymore. As always when talking about pricing, the exact wording is important, so please read the What’s New post for the details.
Introducing Amazon EC2 C7i-flex instances – These instances delivers up to 19 percent better price performance compared to C6i instances. Using C7i-flex instances is the easiest way for you to get price performance benefits for a majority of compute-intensive workloads. The new instances are powered by the 4th generation Intel Xeon Scalable custom processors (Sapphire Rapids) that are available only on AWS and offer 5 percent lower prices compared to C7i.
Application Load Balancer launches IPv6 only support for internet clients – Application Load Balancer now allows customers to provision load balancers without IPv4s for clients that can connect using just IPv6s. To connect, clients can resolve AAAA DNS records that are assigned to Application Load Balancer. The Application Load Balancer is still dual stack for communication between the load balancer and targets. With this new capability, you have the flexibility to use both IPv4s or IPv6s for your application targets while avoiding IPv4 charges for clients that don’t require it.
Amazon VPC Lattice now supports TLS Passthrough – We announced the general availability of TLS passthrough for Amazon VPC Lattice, which allows customers to enable end-to-end authentication and encryption using their existing TLS or mTLS implementations. Prior to this launch, VPC Lattice supported HTTP and HTTPS listener protocols only, which terminates TLS and performs request-level routing and load balancing based on information in HTTP headers.
Amazon DocumentDB zero-ETL integration with Amazon OpenSearch Service – This new integration provides you with advanced search capabilities, such as fuzzy search, cross-collection search and multilingual search, on your Amazon DocumentDB (with MongoDB compatibility) documents using the OpenSearch API. With a few clicks in the AWS Management Console, you can now synchronize your data from Amazon DocumentDB to Amazon OpenSearch Service, eliminating the need to write any custom code to extract, transform, and load the data.
Amazon EventBridge now supports customer managed keys (CMK) for event buses – This capability allows you to encrypt your events using your own keys instead of an AWS owned key (which is used by default). With support for CMK, you now have more fine-grained security control over your events, satisfying your company’s security requirements and governance policies.
Other AWS news Here are some additional news items, open source projects, and Twitch shows that you might find interesting:
The Four Pillars of Managing Email Reputation – Dustin Taylor is the manager of anti-abuse and email deliverability for Amazon Simple Email Service (SES). He wrote a remarkable post exploring Amazon SES approach to managing domain and IP reputation. Maintaining a high reputation ensures optimal recipient inboxing. His post outlines how Amazon SES protects its network reputation to help you deliver high-quality email consistently. A worthy read, even if you’re not sending email at scale. I learned a lot.
Build On Generative AI – Season 3 of your favorite weekly Twitch show about all things generative artificial intelligence (AI) is in full swing! Streaming every Monday, 9:00 AM US PT, my colleagues Tiffany and Darko discuss different aspects of generative AI and invite guest speakers to demo their work.
AWS open source news and updates – My colleague Ricardo writes this weekly open source newsletter, in which he highlights new open source projects, tools, and demos from the AWS Community.
Upcoming AWS events
AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Hong Kong (May 22), Milan (May 23), Stockholm (June 4), and Madrid (June 5).
AWS re:Inforce – Explore 2.5 days of immersive cloud security learning in the age of generative AI at AWS re:Inforce, June 10–12 in Pennsylvania.
AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Midwest | Columbus (June 13), Sri Lanka (June 27), Cameroon (July 13), Nigeria (August 24), and New York (August 28).
This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.


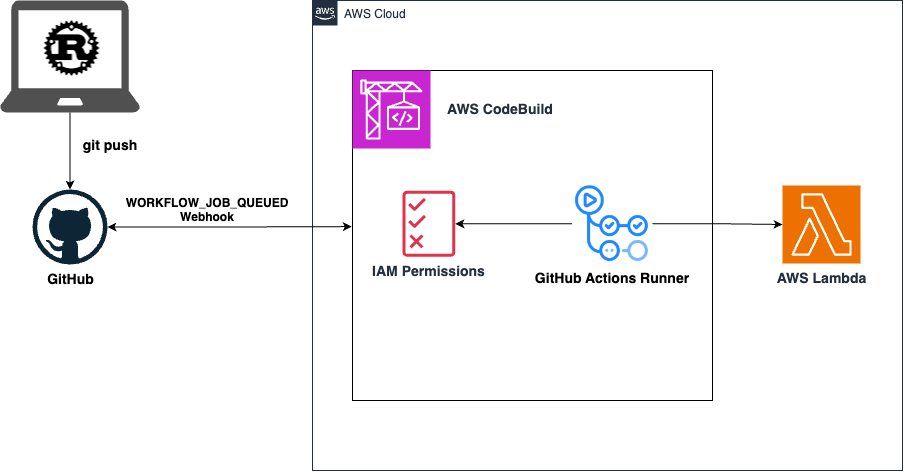

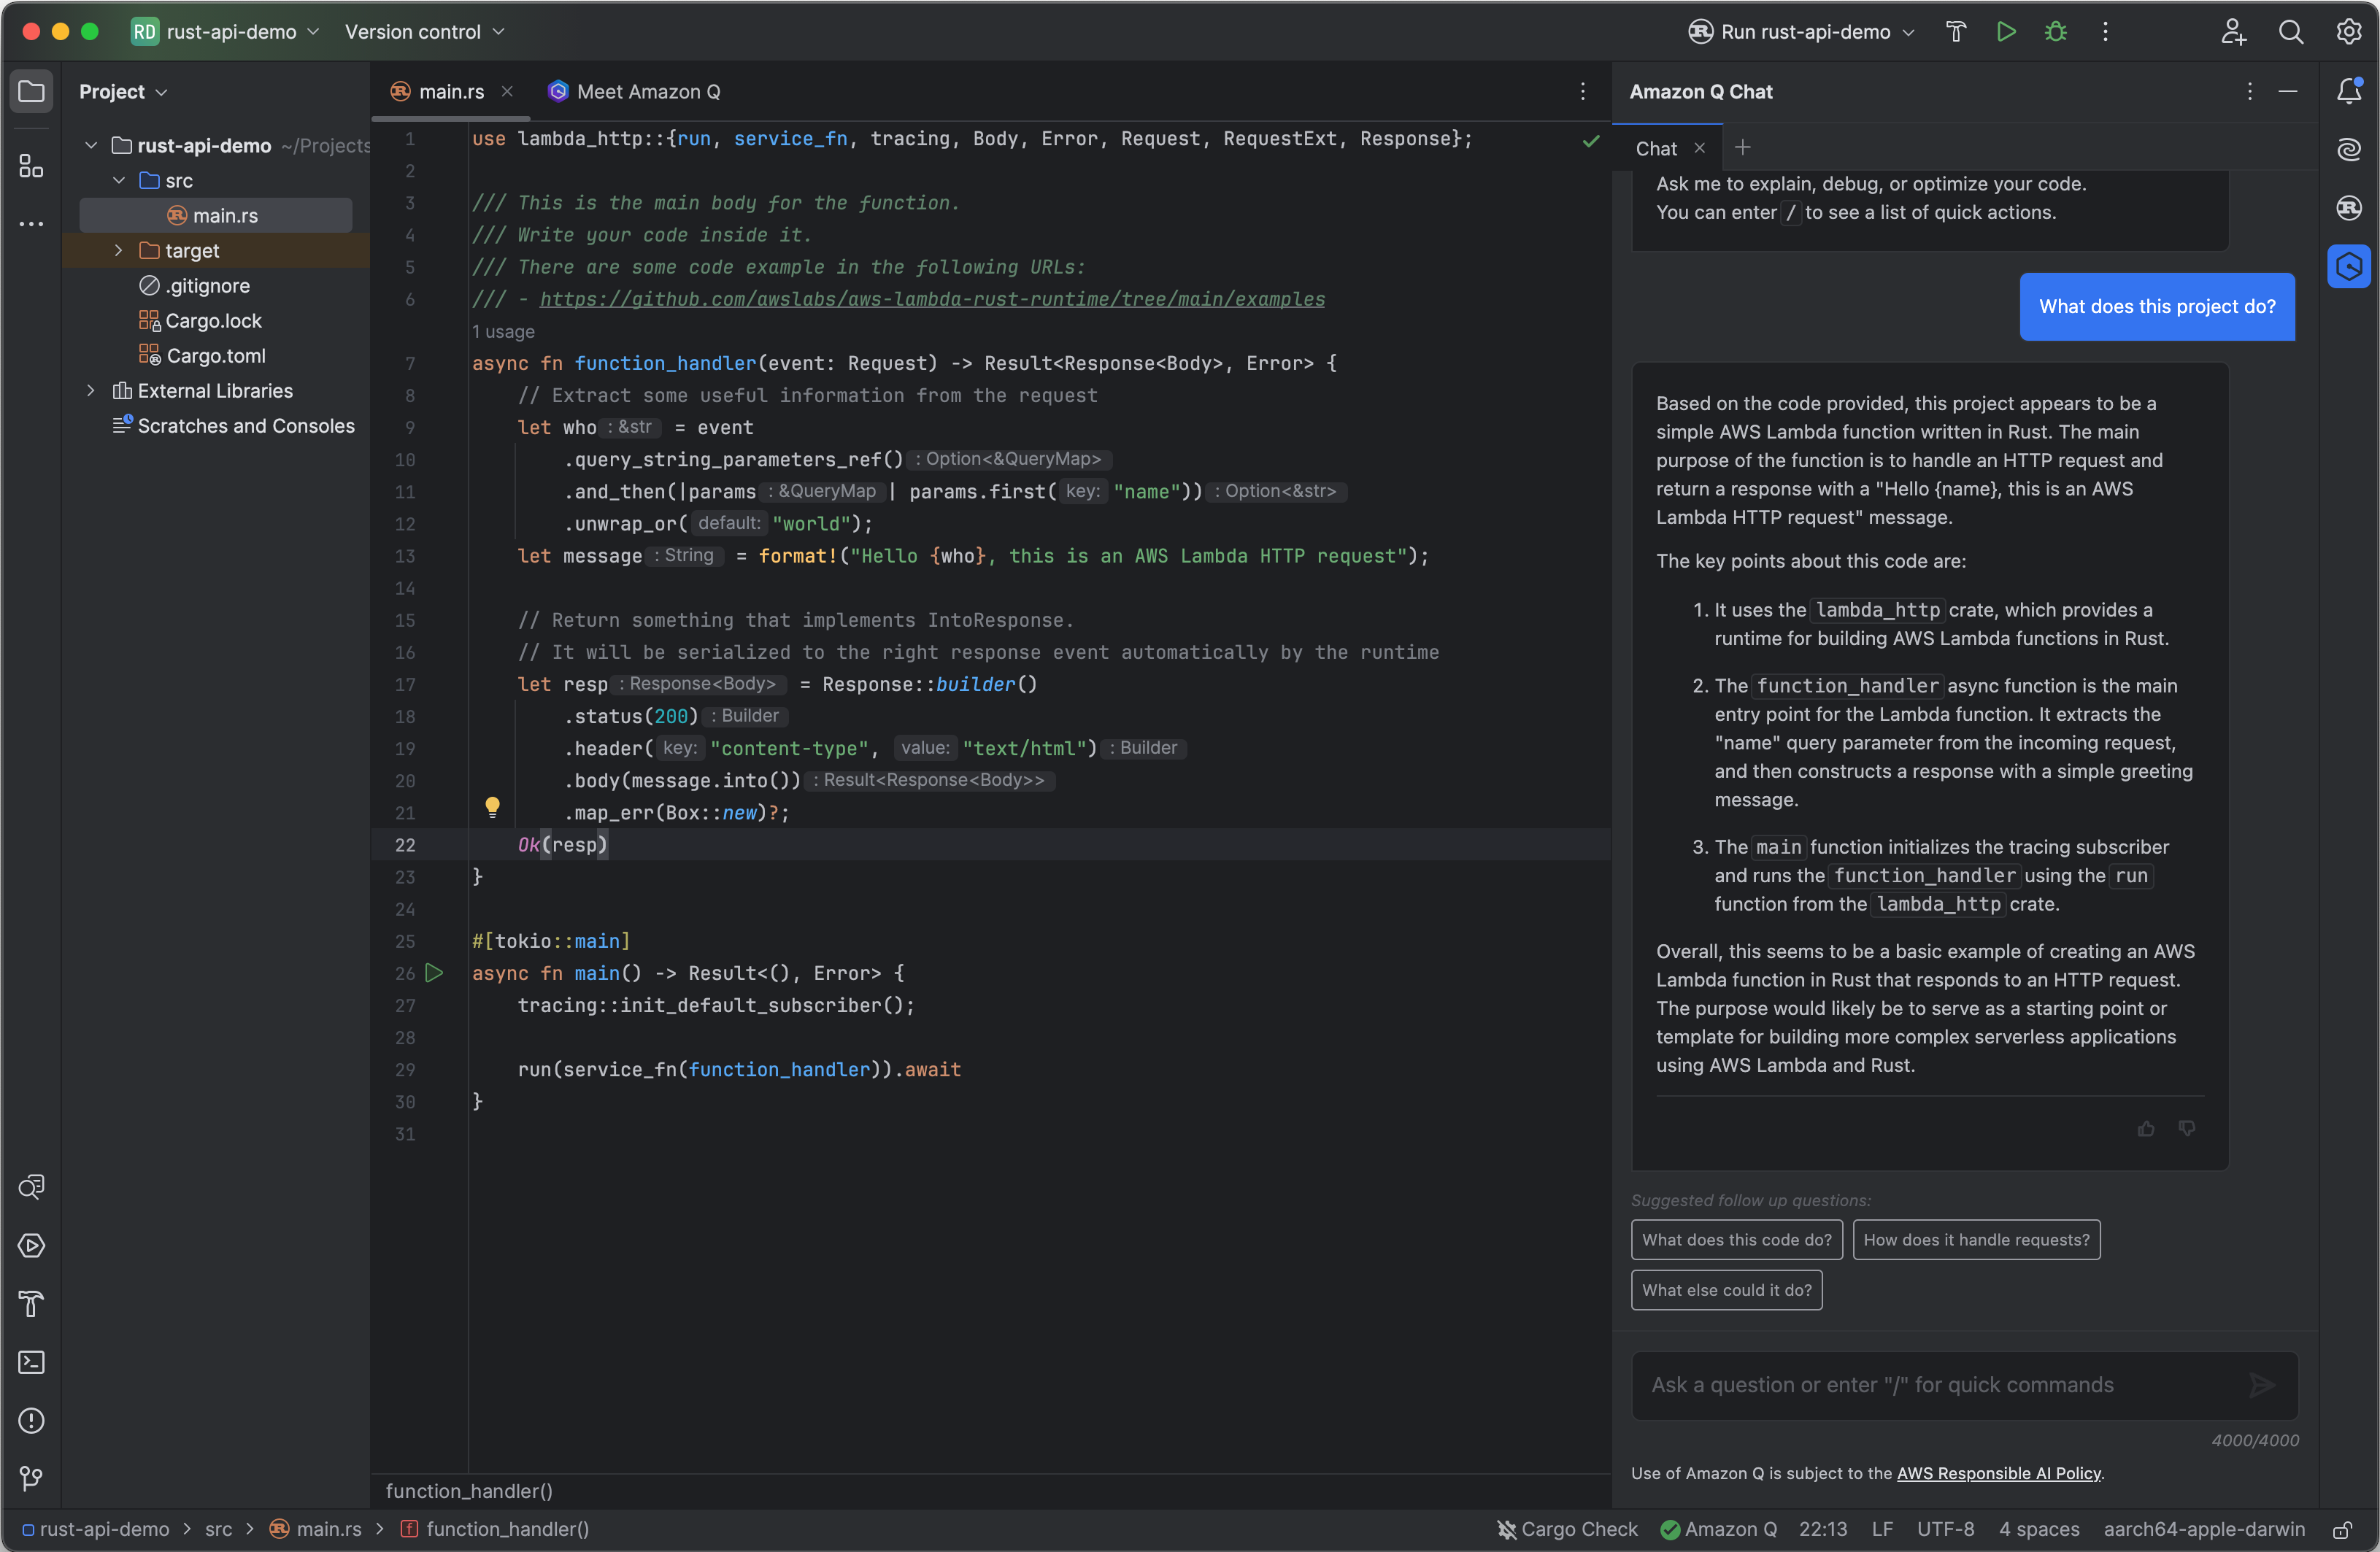

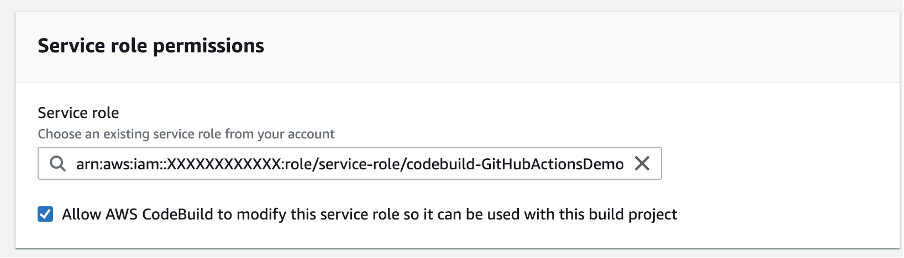

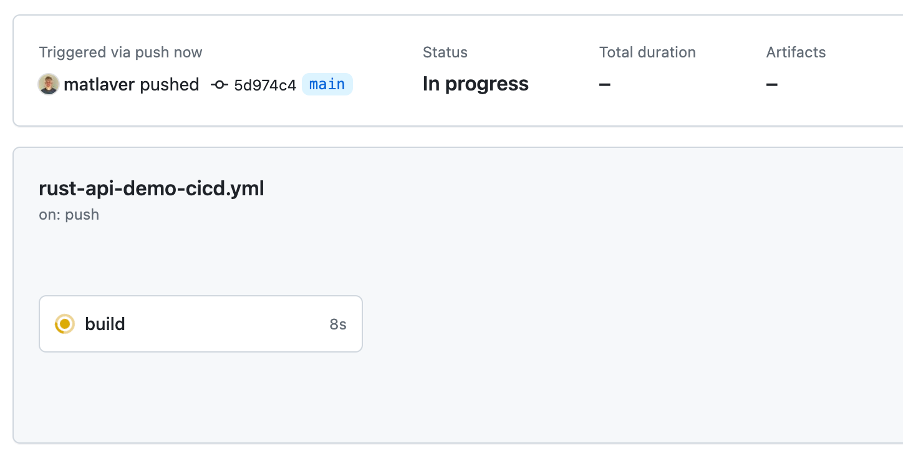
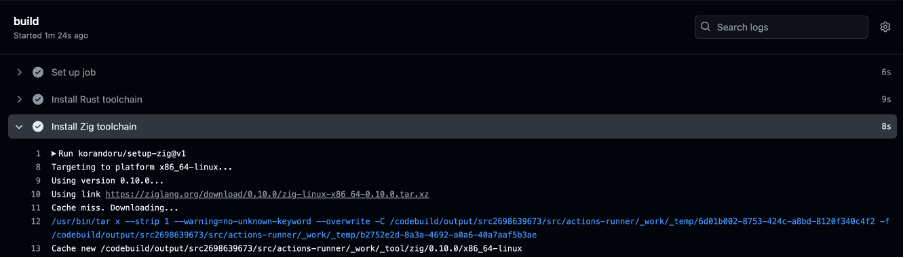
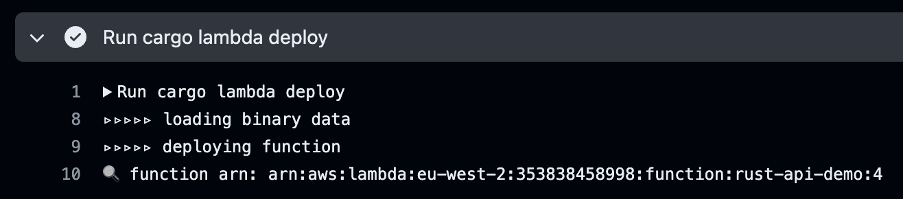
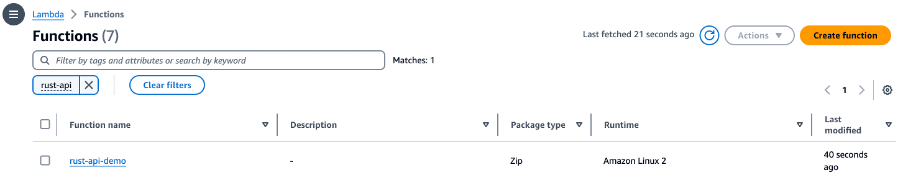
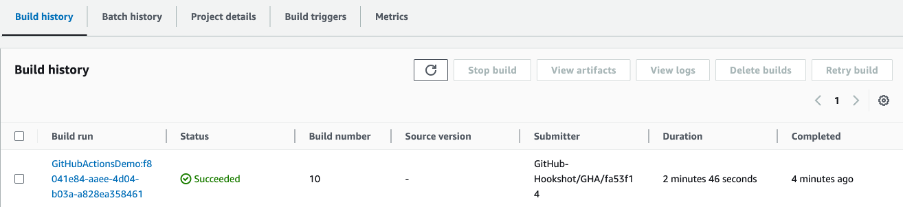
 ” width=”1252″ height=”889″>
 ” width=”1280″ height=”720″>
 ” width=”863″ height=”521″>
 ” width=”865″ height=”582″>
 ” width=”1497″ height=”1173″>
 ” width=”1336″ height=”1313″>
 ” width=”1333″ height=”1364″>


 Kalyan Janaki is Senior Big Data & Analytics Specialist with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS.


 Build On Generative AI — Now streaming every Thursday, 2:00 PM US PT on


Response:
3) Send test message
Response:
Response – (ConflictException):
Conclusion
As SMS messaging continues to play a crucial role in customer engagement and authentication, protecting your communications from AIT is more important than ever. Amazon Pinpoint Protect provides a powerful and user-friendly solution to help you mitigate the impact of SMS pumping, ensuring the integrity of your SMS channels and preserving your business’ reputation and resources. Whether you’re a small business or a large enterprise, Pinpoint Protect is a valuable tool to have in your arsenal as you navigate the evolving landscape of SMS messaging.
To get started with Pinpoint SMS Protect, visit the Amazon Pinpoint SMS documentation or reach out to your AWS account team. And don’t forget to let us know in the comments how Protect configurations has helped you combat AIT and strengthen your SMS communications.
A few resources to help you plan for your SMS program:
About the Author
Brett Ezell is your friendly neighborhood Solutions Architect at AWS, where he specializes in helping customers optimize their SMS and email campaigns using Amazon Pinpoint and Amazon Simple Email Service. As a former US Navy veteran, Brett brings a unique perspective to his work, ensuring customers receive tailored solutions to meet their needs. In his free time, Brett enjoys live music, collecting vinyl, and the challenges of a good workout. And, as a self-proclaimed comic book aficionado, he can often be found combing through his local shop for new books to add to his collection.