Tag Archives: launch

Amazon S3 Metadata now supports metadata for all your S3 objects

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-s3-metadata-now-supports-metadata-for-all-your-s3-objects/

Amazon S3 Metadata now provides complete visibility into all your existing objects in your Amazon Simple Storage Service (Amazon S3) buckets, expanding beyond new objects and changes. With this expanded coverage, you can analyze and query metadata for your entire S3 storage footprint.

Today, many customers rely on Amazon S3 to store unstructured data at scale. To understand what’s in a bucket, you often need to build and maintain custom systems that scan for objects, track changes, and manage metadata over time. These systems are expensive to maintain and hard to keep up to date as data grows.

Since the launch of S3 Metadata at re:Invent 2024, you’ve been able to query new and updated object metadata using metadata tables instead of relying on Amazon S3 Inventory or object-level APIs such as ListObjects, HeadObject, and GetObject—which can introduce latency and impact downstream workflows.

To make it easier for you to work with this expanded metadata, S3 Metadata introduces live inventory tables that work with familiar SQL-based tools. After your existing objects are backfilled into the system, any updates like uploads or deletions typically appear within an hour in your live inventory tables.

With S3 Metadata live inventory tables, you get a fully managed Apache Iceberg table that provides a complete and current snapshot of the objects and their metadata in your bucket, including existing objects, thanks to backfill support. These tables are refreshed automatically within an hour of changes such as uploads or deletions, so you stay up to date. You can use them to identify objects with specific properties—like unencrypted data, missing tags, or particular storage classes—and to support analytics, cost optimization, auditing, and governance.

S3 Metadata journal tables, previously known as S3 Metadata tables, are automatically enabled when you configure live inventory tables, provide a near real-time view of object-level changes in your bucket—including uploads, deletions, and metadata updates. These tables are ideal for auditing activity, tracking the lifecycle of objects, and generating event-driven insights. For example, you can use them to find out which objects were deleted in the past 24 hours, identify the requester making the most PUT operations, or monitor updates to object metadata over time.

S3 Metadata tables are created in a namespace name that is similar to your bucket name for easier discovery. The tables are stored in AWS system table buckets, grouped by account and Region. After you enable S3 Metadata for a general purpose S3 bucket, the system creates and maintains these tables for you. You don’t need to manage compaction or garbage collection processes—S3 Tables takes care of table maintenance tasks in the background.

These new tables help avoid waiting for metadata discovery before processing can begin, making them ideal for large-scale analytics and machine learning (ML) workloads. By querying metadata ahead of time, you can schedule GPU jobs more efficiently and reduce idle time in compute-intensive environments.

Let’s see how it works
To see how this works in practice, I configure S3 Metadata for a general purpose bucket using the AWS Management Console.

S3 Metadata, start from general purpose bucket

After choosing a general purpose bucket, I choose the Metadata tab, then I choose Create metadata configuration.
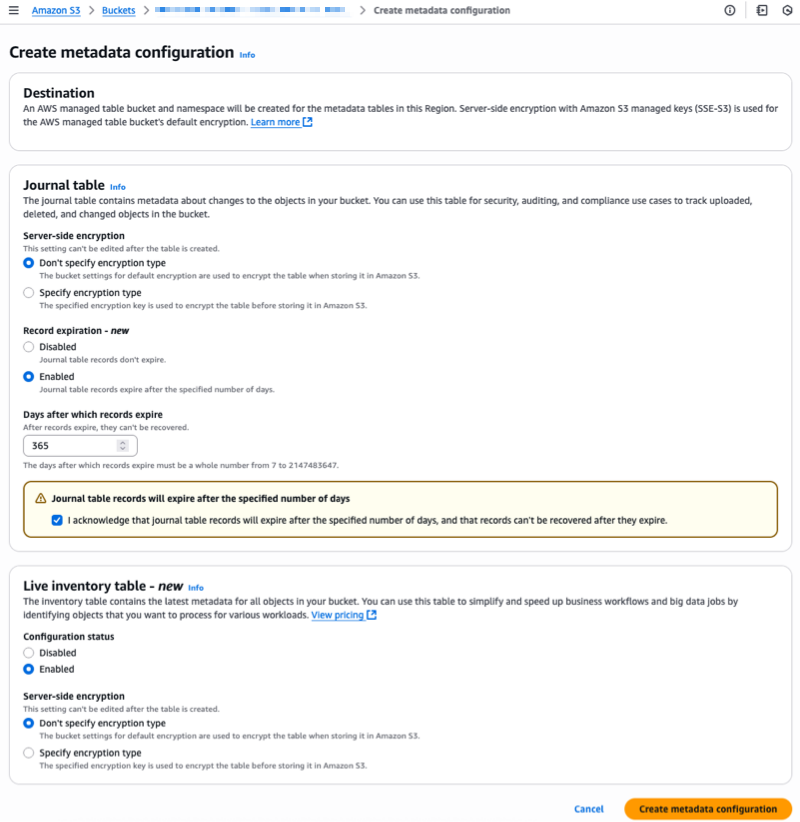
S3 Metadata, configure journal and inventory tableFor Journal table, I can choose the Server-side encryption option and the Record expiration period. For Live Inventory table, I choose Enabled and I can select the Server-side encryption options.

I configure Record expiration on the journal table. Journal table records expire after the specified number of days, 365 days (one year) in my example.

Then, I choose Create metadata configuration.
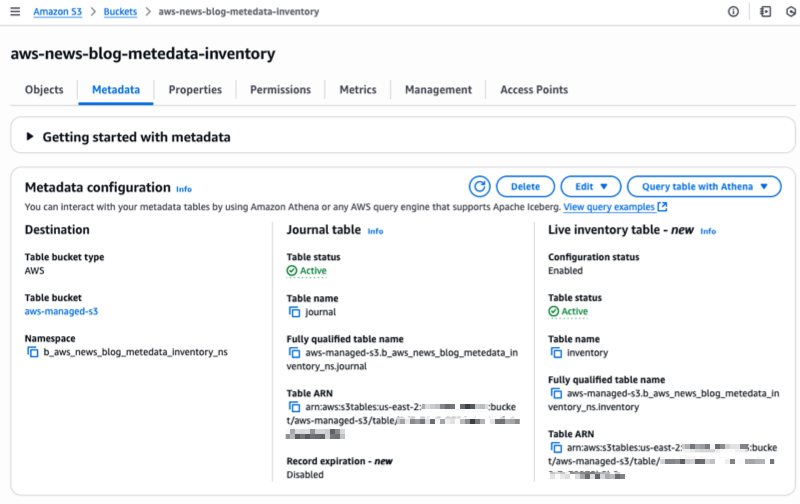
S3 Metadata, backfilling

S3 Metadata creates the live inventory table and journal table. In the Live Inventory table section, I can observe the Table status: the system immediately starts to backfill the table with existing object metadata. It can take between minutes to hours. The exact time depends on the quantity of objects you have in your S3 bucket.

While waiting, I also upload and delete objects to generate data in the journal table.

Then, I navigate to Amazon Athena to start querying the new tables.
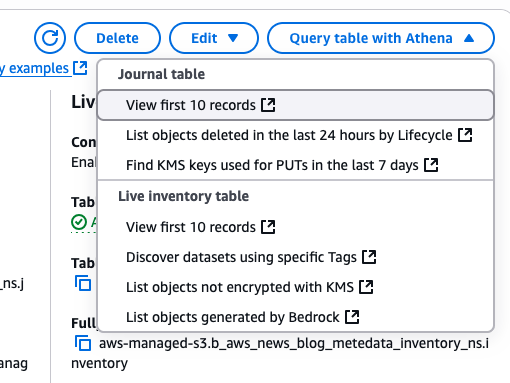
S3 Metadata, query with Athena

I choose Query table with Athena to start querying the table. I can choose between a couple of default queries on the console.
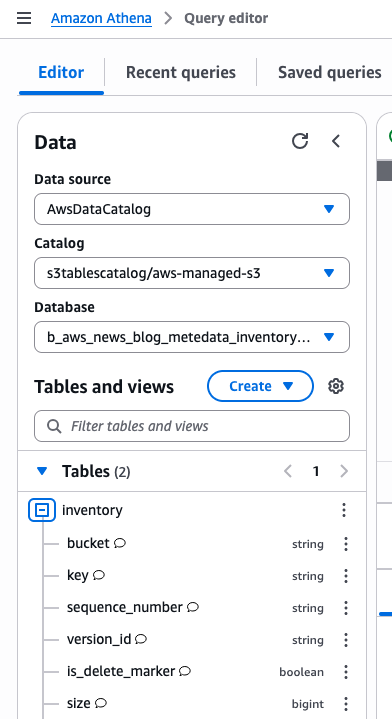
S3 MetaData table structure

In Athena, I observe the structure of the tables in the AWSDataCatalog Data source and I start with a short query to check how many records are available in the journal table. I already have 6,488 entries:

SELECT count(*) FROM "b_aws_news_blog_metadata_inventory_ns"."journal";

# _col0
1 6488

Here are a couple of example queries I tried on the journal table:

# Query deleted objects in last 24 hours
# Use is_delete_marker=true for versioned buckets and record_type='DELETE' otherwise
SELECT bucket, key, version_id, last_modified_date
FROM "s3tablescatalog/aws-managed-s3"."b_aws_news_blog_metadata_inventory_ns"."journal"
WHERE last_modified_date >= (current_date - interval '1' day) AND is_delete_marker = true;

# bucket key version_id last_modified_date is_delete_marker
1 aws-news-blog-metadata-inventory .build/index-build/arm64-apple-macosx/debug/index/store/v5/records/G0/NSURLSession.h-JET61D329FG0 
2 aws-news-blog-metadata-inventory .build/index-build/arm64-apple-macosx/debug/index/store/v5/records/G5/cdefs.h-PJ21EUWKMWG5 
3 aws-news-blog-metadata-inventory .build/index-build/arm64-apple-macosx/debug/index/store/v5/records/FX/buf.h-25EDY57V6ZXFX 
4 aws-news-blog-metadata-inventory .build/index-build/arm64-apple-macosx/debug/index/store/v5/records/G6/NSMeasurementFormatter.h-3FN8J9CLVMYG6 
5 aws-news-blog-metadata-inventory .build/index-build/arm64-apple-macosx/debug/index/store/v5/records/G8/NSXMLDocument.h-1UO2NUJK0OAG8 

# Query recent PUT requests IP addresses
SELECT source_ip_address, count(source_ip_address)
FROM "s3tablescatalog/aws-managed-s3"."b_aws_news_blog_metadata_inventory_ns"."journal"
GROUP BY source_ip_address;

#	source_ip_address	_col1
1	my_laptop_IP_address	12488

# Query S3 Lifecycle expired objects in last 7 days
SELECT bucket, key, version_id, last_modified_date, record_timestamp
FROM "s3tablescatalog/aws-managed-s3"."b_aws_news_blog_metadata_inventory_ns"."journal"
WHERE requester = 's3.amazonaws.com' AND record_type = 'DELETE' AND record_timestamp > (current_date - interval '7' day);

(not applicable to my demo bucket)

The results helped me track the specific objects that were removed, including their timestamps.

Now, I look at the live inventory table:

# Distribution of object tags
SELECT object_tags, count(object_tags)
FROM "s3tablescatalog/aws-managed-s3"."b_aws_news_blog_metadata_inventory_ns"."inventory"
GROUP BY object_tags;

# object_tags    _col1
1 {Source=Swift} 1
2 {Source=swift} 1
3 {}             12486

# Query storage class and size for specific tags
SELECT storage_class, count(*) as count, sum(size) / 1024 / 1024 as usage
FROM "s3tablescatalog/aws-managed-s3"."b_aws_news_blog_metadata_inventory_ns"."inventory"
GROUP BY object_tags['pii=true'], storage_class;

# storage_class count   usage
1 STANDARD      124884  165

# Find objects with specific user defined metadata
SELECT key, last_modified_date, user_metadata
FROM "s3tablescatalog/aws-managed-s3"."b_aws_news_blog_metadata_inventory_ns"."inventory"
WHERE cardinality(user_metadata) > 0 ORDER BY last_modified_date DESC;

(not applicable to my demo bucket)

These are just a few examples of what is possible with S3 Metadata. Your preferred queries will depend on your use cases. Refer to Analyzing Amazon S3 Metadata with Amazon Athena and Amazon QuickSight in the AWS Storage Blog for more examples.

Pricing and availability
S3 Metadata live inventory and journal tables are available today in US East (Ohio, N. Virginia) and US West (N. California).

The journal tables are charged $0.30 per million updates. This is a 33 percent drop from our previous price.

For inventory tables, there’s a one-time backfill cost of $0.30 for a million objects to set up the table and generate metadata for existing objects. There are no additional costs if your bucket has less than one billion objects. For buckets with more than a billion objects, there is a monthly fee of $0.10 per million objects per month.

As usual, the Amazon S3 pricing page has all the details.

With S3 Metadata live inventory and journal tables, you can reduce the time and effort required to explore and manage large datasets. You get an up-to-date view of your storage and a record of changes, and both are available as Iceberg tables you can query on demand. You can discover data faster, power compliance workflows, and optimize your ML pipelines.

You can get started by enabling metadata inventory on your S3 bucket through the AWS console, AWS Command Line Interface (AWS CLI), or AWS SDKs. When they’re enabled, the journal and live inventory tables are automatically created and updated. To learn more, visit the S3 Metadata Documentation page.
— seb

TwelveLabs video understanding models are now available in Amazon Bedrock

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/twelvelabs-video-understanding-models-are-now-available-in-amazon-bedrock/

Earlier this year, we preannounced that TwelveLabs video understanding models were coming to Amazon Bedrock. Today, we’re announcing the models are now available for searching through videos, classifying scenes, summarizing, and extracting insights with precision and reliability.

TwelveLabs has introduced Marengo, a video embedding model proficient at performing tasks such as search and classification, and Pegasus, a video language model that can generate text based on video data. These models are trained on Amazon SageMaker HyperPod to deliver groundbreaking video analysis that provides text summaries, metadata generation, and creative optimization.

With the TwelveLabs models in Amazon Bedrock, you can find specific moments using natural language video search capabilities like “show me the first touchdown of the game” or “find the scene where the main characters first meet” and instantly jump to those exact moments. You can also build applications to understand video content by generating descriptive text such as titles, topics, hashtags, summaries, chapters, or highlights for discovering insights and connections without requiring predefined labels or categories.

For example, you can find recurring themes in customer feedback or spot product usage patterns that weren’t obvious before. Whether you have hundreds or thousands of hours of video content, you can now transform that entire library into a searchable knowledge resource while maintaining enterprise-grade security and performance.

Let’s take a look at the Marengo and Pegasus videos that TwelveLabs has published.

You can transform video workflows with these models across industries. Media producers and editors can instantly locate specific scenes or dialogue, which means you can focus on storytelling rather than sifting through hours of footage. Marketing teams are streamlining their advertising workflows by quickly personalizing content to resonate with various audiences, while security teams are using the technology to proactively identify potential risks by spotting patterns across multiple video feeds.

Getting started with TwelveLabs models in Amazon Bedrock
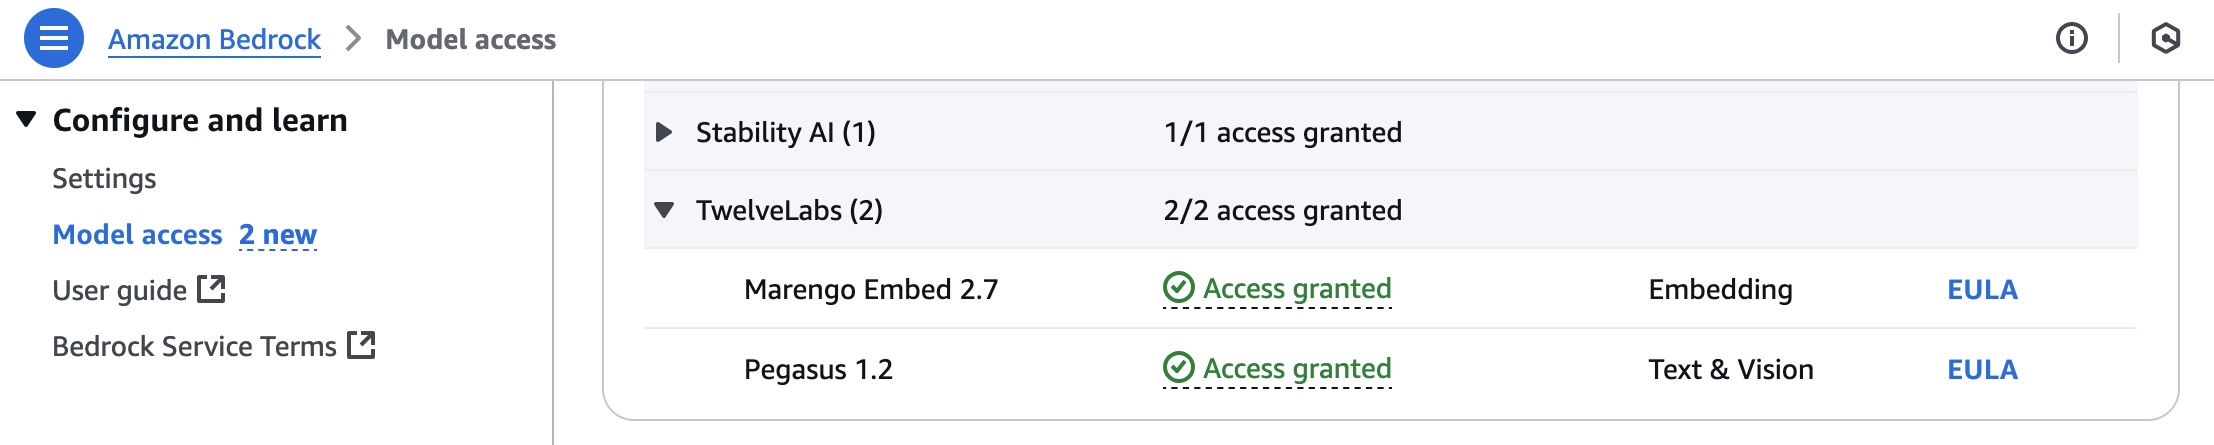
Before getting started, if you’re new to using TwelveLabs models, go to the Amazon Bedrock console and choose Model access in the bottom left navigation pane. To access the latest TwelveLabs models, request access for Marengo Embed 2.7 and Pegasus 1.2 in TwelveLabs.

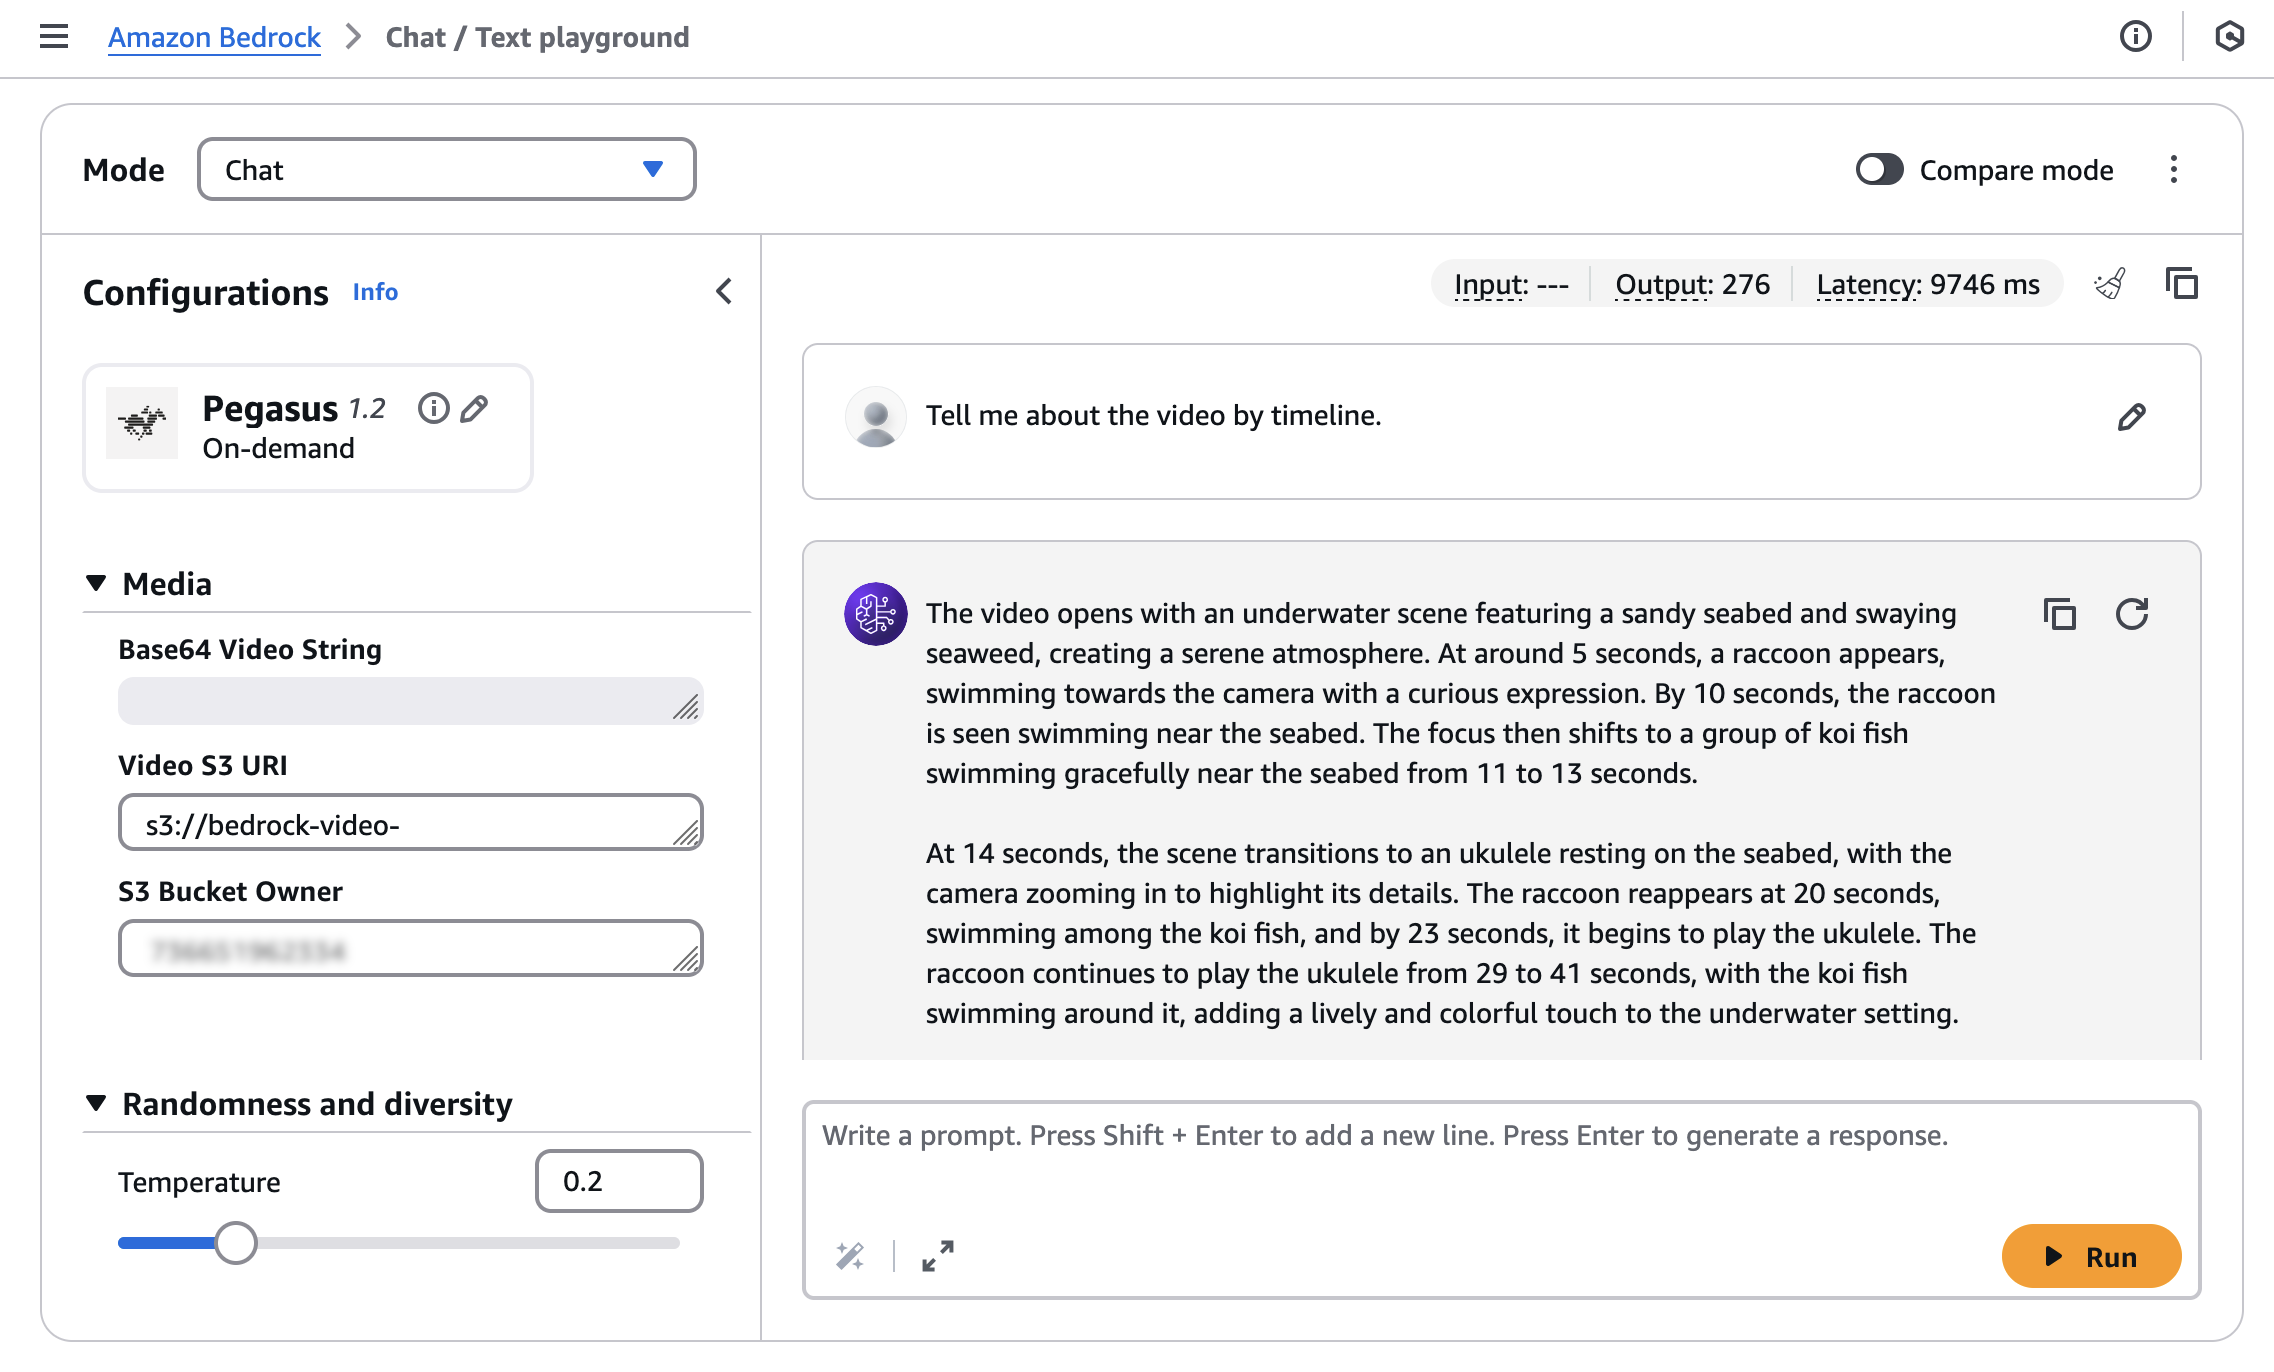
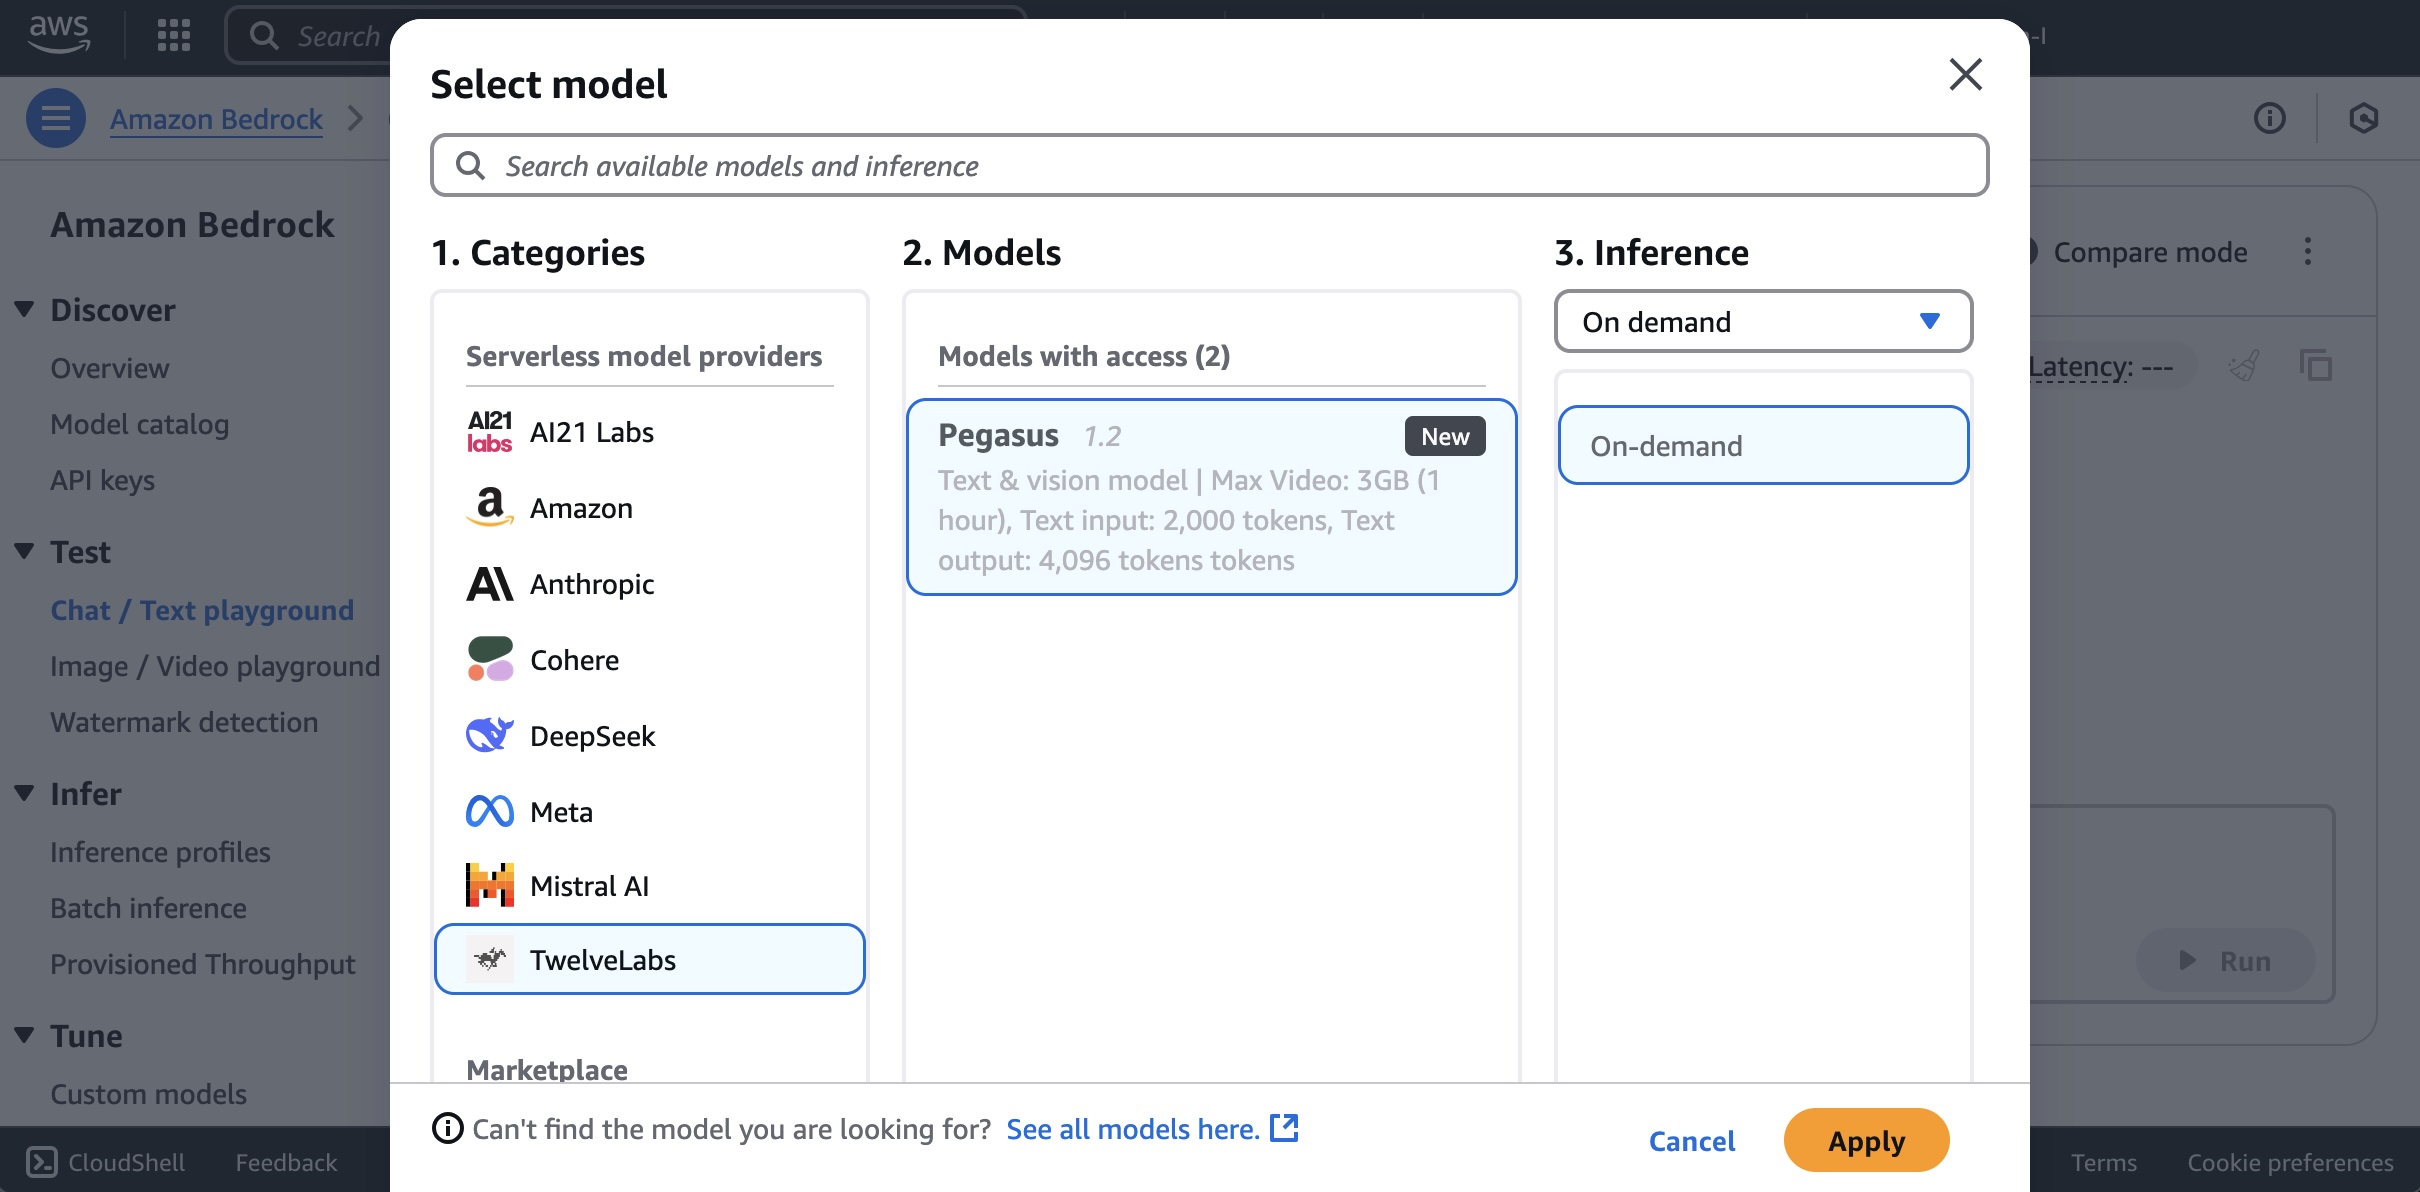
To use TwelveLabs models in Amazon Bedrock, choose Chat/Text Playground under Test in the left navigation pane. Choose Select model, select TwelveLabs as the category and Pegasus as the model, and then choose Apply.

For searching or generating text from your video, you should upload your video to an Amazon Simple Storage Service (Amazon S3) bucket or input Base64-formatted video string.

I will use a sample video generated with Amazon Nova Reel with a prompt: “A cute raccoon playing guitar underwater.”

Enter the S3 URI of your uploaded video and the S3 Bucket Owner, and then run your prompt: “Tell me about the video by timeline”.

You can get following model response:

The video opens with an underwater scene featuring a sandy seabed and swaying seaweed, creating a serene atmosphere. At around 5 seconds, a raccoon appears, swimming towards the camera with a curious expression. By 10 seconds, the raccoon is seen swimming near the seabed. The focus then shifts to a group of koi fish swimming gracefully near the seabed from 11 to 13 seconds.

At 14 seconds, the scene transitions to an ukulele resting on the seabed, with the camera zooming in to highlight its details. The raccoon reappears at 20 seconds, swimming among the koi fish, and by 23 seconds, it begins to play the ukulele. The raccoon continues to play the ukulele from 29 to 41 seconds, with the koi fish swimming around it, adding a lively and colorful touch to the underwater setting.

From 42 to 49 seconds, the raccoon is shown playing the ukulele with the koi fish swimming around it. The video concludes with a screen displaying "Video generated with Amazon Novo Reel 1.1" and "Available in Amazon Bedrock" from 50 to 54 seconds, followed by the AWS logo from 55 to 57 seconds.

The TwelveLabs models can be easily integrated into your applications using the Amazon Bedrock Converse API, which provides a unified interface for conversational AI interactions.

Here’s an example of how to use the AWS SDK for Python (Boto3) with the TwelveLabs Pegasus model:

import boto3
import json
import os

AWS_REGION = "us-east-1"
MODEL_ID = "twelvelabs.pegasus-1-2-v1:0"
VIDEO_PATH = "sample.mp4"

def read_file(file_path: str) -> bytes:
    """Read a file in binary mode."""
    try:
        with open(file_path, 'rb') as file:
            return file.read()
    except Exception as e:
        raise Exception(f"Error reading file {file_path}: {str(e)}")

bedrock_runtime = boto3.client(
    service_name="bedrock-runtime",
    region_name=AWS_REGION
)

request_body = {
    "messages": [
        {
            "role": "user",
            "content": [
                {
                    "inputPrompt": "tell me about the video",
                    "mediaSource: {
                        "base64String": read_file(VIDEO_PATH)
                    }
                },
            ],
        }
    ]
}

response = bedrock_runtime.converse(
    modelId=MODEL_ID,
    messages=request_body["messages"]
)

print(response["output"]["message"]["content"][-1]["text"])

The TwelveLabs Marengo Embed 2.7 model generates vector embeddings from video, text, audio, or image inputs. These embeddings can be used for similarity search, clustering, and other machine learning (ML) tasks. The model supports asynchronous inference through the Bedrock AsyncInvokeModel API.

For video source, you can request JSON format for the TwelveLabs Marengo Embed 2.7 model using the AsyncInvokeModel API.

{
    "modelId": "twelvelabs.marengo-embed-2.7",
    "modelInput": {
        "inputType": "video",
        "mediaSource": {
            "s3Location": {
                "uri": "s3://your-video-object-s3-path",
                "bucketOwner": "your-video-object-s3-bucket-owner-account"
            }
        }
    },
    "outputDataConfig": {
        "s3OutputDataConfig": {
            "s3Uri": "s3://your-bucket-name"
        }
    }
}

You can get a response delivered to the specified S3 location.

{
    "embedding": [0.345, -0.678, 0.901, ...],
    "embeddingOption": "visual-text",
    "startSec": 0.0,
    "endSec": 5.0
}

To help you get started, check out a broad range of code examples for multiple use cases and a variety of programming languages. To learn more, visit TwelveLabs Pegasus 1.2 and TwelveLabs Marengo Embed 2.7 in the AWS Documentation.

Now available
TwelveLabs models are generally available today in Amazon Bedrock: the Marengo model in the US East (N. Virginia), Europe (Ireland), and Asia Pacific (Seoul) Region, and the Pegasus model in US West (Oregon), and Europe (Ireland) Region accessible with cross-Region inference from US and Europe Regions. Check the full Region list for future updates. To learn more, visit the TwelveLabs in Amazon Bedrock product page and the Amazon Bedrock pricing page.

Give TwelveLabs models a try on the Amazon Bedrock console today, and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: AWS Builder Center, Amazon Q, Oracle Database@AWS, and more (July 14, 2025)

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-builder-center-amazon-q-oracle-databaseaws-and-more-july-14-2025/

Summer is well and truly here in the UK! I’m a bit of a summer grinch though so, unlike most people, I’m not crazy about “the glorious sun” scorching me when I’m out and about. On the upside, this provides the perfect excuse to retreat to the comfort of a well-ventilated room where I can focus on coding and curating the latest AWS releases to bring you the highlights.

I also managed to escape the heat for most of yesterday while recording an episode for the AWS Developers Podcast where the wonderful Sebastien Stormaq and Tiffany Souterre interviewed me about games development. If you haven’t discovered it yet, I highly recommend you give it a go as the episodes are full of interesting lessons and insights from not just AWS, but customers and community members who share their stories and expertise in a relaxed conversation.

Alright, ready to discover some of the new things we released last week? Here are the highlights.

AWS Builder Center
There is a new home for AWS builders and community members! AWS Builder Center is a new place where cloud builders can connect, share knowledge, and access resources to enhance their AWS journey. The platform enables users to join community programs, discover trending topics, access AWS Skill Builder courses, participate in technical challenges, and more, using a single Builder ID sign-in.

One the features that I’m personally most excited about is the Wishlist. You can now create wishes and tell AWS directly about ways to improve our products and services or share original ideas that you think could help you and your teams. You can also browse and upvote existing wishes to support any suggestions that you think should be prioritized. The AWS teams will keep an eye on this and if a wish has enough traction it may just be considered!

Read the news blog post for a quick tour through some of the most exciting features or head over to AWS Builder Center and start exploring!

AI
The world of AI keeps moving fast and changing our world, by providing new and exciting ways to do things and become more productive. Here are two releases from last week that caught my attention.

  • Amazon Q chat in the AWS Management Console can now query AWS service data – Amazon Q Developer expands its capabilities by enabling natural language queries of data stored across AWS services like S3, DynamoDB, and CloudWatch, directly from the AWS Console, Slack, Microsoft Teams, and AWS Console Mobile Application. This enhancement streamlines cloud management and troubleshooting by allowing users to access and analyze service data through conversational interfaces, with access controls managed through IAM permissions.
  • Amazon CloudWatch and Application Signals MCP servers for AI-assisted troubleshooting – AWS has released two new Model Context Protocol (MCP) servers – CloudWatch MCP and Application Signals MCP – that enable AI agents to leverage observability data for automated troubleshooting through conversational interfaces. These open-source servers allow AI assistants to analyze metrics, alarms, logs, traces, and service health data across AWS environments, streamlining incident response and root cause analysis without requiring developers to manually navigate multiple AWS consoles.

Oracle Database@AWS
It seems like yesterday when Andy Jassy announced our partnership with Oracle to create Oracle Database@AWS, a jointly offered service that runs Oracle databases on Exadata infrastructure directly within AWS data centers, providing a unified AWS-Oracle experience. Fast forward to last week and Oracle Database@AWS has reached a significant milestone with its general availability release. It is now available in US East (N. Virginia) and US West (Oregon) regions, with plans to expand to 20 additional regions globally.

In addition, VPC Lattice has added support for Oracle Database@AWS enabling seamless connectivity between applications in VPCs and on-premises environments to Oracle database networks. The integration simplifies network management and provides secure access from Oracle Database@AWS to AWS services like Amazon S3 and Amazon Redshift, without requiring complex networking setup.

So if you’re looking to migrate your Oracle database workloads, now is a great time to explore Oracle Database@AWS as it offers a compelling path forward with minimal modifications required.

Additional highlights
Here are some other releases that I think many people will be happy about.

  • AWS Config now supports 12 new resource types – AWS Config has expanded its monitoring capabilities with support for 12 new resource types across services including BackupGateway, CloudFront, EntityResolution, Bedrock, and more. These additions are automatically tracked if you have enabled recording for all resource types, enhancing your ability to discover, assess, and audit AWS resources.
  • Amazon SageMaker Studio now supports remote connections from Visual Studio Code – Amazon SageMaker Studio now supports remote connections from Visual Studio Code, allowing developers to use their familiar VS Code setup while leveraging SageMaker’s scalable compute resources for AI development.
  • AWS Network Firewall: Native AWS Transit Gateway support in all regions – AWS Network Firewall now offers native integration with AWS Transit Gateway across all supported regions, enabling direct attachment and simplified traffic inspection between VPCs and on-premises networks. This integration eliminates the need for managing dedicated VPC subnets and route tables while providing multi-AZ redundancy for improved security and reliability.

Upcoming AWS Events
AWS Summit New York – this is definitely one to watch…literally! Registrations are closed due to capacity but you can tune in to watch live all the announcements and launches! No spoilers, but, trust me, there are a quite a few exciting things in store, so make sure to check it out.

AWS Gen AI Lofts – AWS Gen AI Lofts are multi-day events offering hands-on workshops, expert guidance, and networking opportunities for developers and business leaders looking to explore or advance their generative AI journey. These events are hosted across multiple global locations including San Francisco, Berlin, Dubai, Dublin, Bengaluru, Manchester, Paris, and Tel Aviv, providing accessible opportunities to accelerate your generative AI adoption.

And that’s it for this week! Come back next Monday for more highlights and keep your AWS knowledge up to date as we cover the latest releases.

Matheus Guimaraes | @codingmatheus

New Amazon EC2 P6e-GB200 UltraServers accelerated by NVIDIA Grace Blackwell GPUs for the highest AI performance

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-p6e-gb200-ultraservers-powered-by-nvidia-grace-blackwell-gpus-for-the-highest-ai-performance/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) P6e-GB200 UltraServers, accelerated by NVIDIA GB200 NVL72 to offer the highest GPU performance for AI training and inference. Amazon EC2 UltraServers connect multiple EC2 instances using a dedicated, high-bandwidth, and low-latency accelerator interconnect across these instances.

The NVIDIA Grace Blackwell Superchips connect two high-performance NVIDIA Blackwell tensor core GPUs and an NVIDIA Grace CPU based on Arm architecture using the NVIDIA NVLink-C2C interconnect. Each Grace Blackwell Superchip delivers 10 petaflops of FP8 compute (without sparsity) and up to 372 GB HBM3e memory. With the superchip architecture, GPU and CPU are colocated within one compute module, increasing bandwidth between GPU and CPU significantly compared to current generation EC2 P5en instances.

With EC2 P6e-GB200 UltraServers, you can access up to 72 NVIDIA Blackwell GPUs within one NVLink domain to use 360 petaflops of FP8 compute (without sparsity) and 13.4 TB of total high bandwidth memory (HBM3e). Powered by the AWS Nitro System, P6e-GB200 UltraServers are deployed in EC2 UltraClusters to securely and reliably scale to tens of thousands of GPUs.

EC2 P6e-GB200 UltraServers deliver up to 28.8 Tbps of total Elastic Fabric Adapter (EFAv4) networking. EFA is also coupled with NVIDIA GPUDirect RDMA to enable low-latency GPU-to-GPU communication between servers with operating system bypass.

EC2 P6e-GB200 UltraServers specifications
EC2 P6e-GB200 UltraServers are available in sizes ranging from 36 to 72 GPUs under NVLink. Here are the specs for EC2 P6e-GB200 UltraServers:

UltraServer type GPUs
GPU
memory (GB)
vCPUs Instance memory
(GiB)
Instance storage (TB) Aggregate EFA Network Bandwidth (Gbps) EBS bandwidth (Gbps)
u-p6e-gb200x36 36 6660 1296 8640 202.5 14400 540
u-p6e-gb200x72 72 13320 2592 17280 405 28800 1080

P6e-GB200 UltraServers are ideal for the most compute and memory intensive AI workloads, such as training and inference of frontier models, including mixture of experts models and reasoning models, at the trillion-parameter scale.

You can build agentic and generative AI applications, including question answering, code generation, video and image generation, speech recognition, and more.

P6e-GB200 UltraServers in action
You can use EC2 P6e-GB200 UltraServers in the Dallas Local Zone through EC2 Capacity Blocks for ML. The Dallas Local Zone (us-east-1-dfw-2a) is an extension of the US East (N. Virginia) Region.

To reserve your EC2 Capacity Blocks, choose Capacity Reservations on the Amazon EC2 console. You can select Purchase Capacity Blocks for ML and then choose your total capacity and specify how long you need the EC2 Capacity Block for u-p6e-gb200x36 or u-p6e-gb200x72 UltraServers.

Once Capacity Block is successfully scheduled, it is charged up front and its price doesn’t change after purchase. The payment will be billed to your account within 12 hours after you purchase the EC2 Capacity Blocks. To learn more, visit Capacity Blocks for ML in the Amazon EC2 User Guide.

To run instances within your purchased Capacity Block, you can use AWS Management Console, AWS Command Line Interface (AWS CLI) or AWS SDKs. On the software side, you can start with the AWS Deep Learning AMIs. These images are preconfigured with the frameworks and tools that you probably already know and use: PyTorch, JAX, and a lot more.

You can also integrate EC2 P6e-GB200 UltraServers seamlessly with various AWS managed services. For example:

  • Amazon SageMaker Hyperpod provides managed, resilient infrastructure that automatically handles the provisioning and management of P6e-GB200 UltraServers, replacing faulty instances with preconfigured spare capacity within the same NVLink domain to maintain performance.
  • Amazon Elastic Kubernetes Services (Amazon EKS) allows one managed node group to span across multiple P6e-GB200 UltraServers as nodes, automating their provisioning and lifecycle management within Kubernetes clusters. You can use EKS topology-aware routing for P6e-GB200 UltraServers, enabling optimal placement of tightly coupled components of distributed workloads within a single UltraServer’s NVLink-connected instances.
  • Amazon FSx for Lustre file systems provide data access for P6e-GB200 UltraServers at the hundreds of GB/s of throughput and millions of input/output operations per second (IOPS) required for large-scale HPC and AI workloads. For fast access to large datasets, you can use up to 405 TB of local NVMe SSD storage or virtually unlimited cost-effective storage with Amazon Simple Storage Service (Amazon S3).

Now available
Amazon EC2 P6e-GB200 UltraServers are available today in the Dallas Local Zone (us-east-1-dfw-2a) through EC2 Capacity Blocks for ML. For more information, visit the Amazon EC2 pricing page.

Give Amazon EC2 P6e-GB200 UltraServers a try in the Amazon EC2 console. To learn more, visit the Amazon EC2 P6e instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

Introducing AWS Builder Center: A new home for the AWS builder community

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-aws-builder-center-a-new-home-for-the-aws-builder-community/

We really love builders at AWS. We’re constantly thinking of new ways to help technical communities thrive and create spaces like AWS Developer Center and community.aws where people can connect and share their knowledge and experiences.

Today, we’re announcing AWS Builder Center, a new home for builders to access all builder resources, engage with the AWS community, and provide feedback or product suggestions to AWS product teams. This new experience also integrates the previous AWS Developer Center and community.aws.

There are a variety of exciting features so let us discover some of them.

Your voice matters: Introducing Wishlist
One of the most exciting new features, in my opinion, is Wishlist. You can now submit your wishes for new features or improvements you’d like to see in AWS services. Others can discover and vote on these wishes while also creating their own.

You can influence product roadmap collectively as a community and help us shape the future of AWS services. You can share ideas, suggestions, feature proposals, or challenges while operating AWS services, with the ability for the AWS community to upvote ideas and highlight the most sought-after improvements. Our internal teams will keep an eye on these and bring the most popular wishes to the attention of our service teams, making your voice an integral part of our product development process.

Connect people in the AWS community
On the Connect page, you’ll find many opportunities to connect directly with AWS Heroes and AWS Community Builders. You can explore and join AWS User Groups and AWS Cloud Clubs near your cities around the world.

On top of that, you can bookmark this page as your centralized hub for finding upcoming community events, making it easy to find opportunities to learn and network in your local area and meet like-minded builders who share your interests.

Speaking of following people, AWS Builder Center makes it really straightforward to connect and engage with others, serving as the central hub for the AWS technical community. It brings together all the different ways that you can connect with fellow builders. For example, the Who to Follow section introduces you to AWS Heroes, Community Builders, and active community members who are sharing their knowledge and expertise in your areas of interest.

Explore our AWS hands-on resources
On the Build page, you’ll discover ways to get familiar with AWS with hands-on experience such as interactive learning resources designed for every skill level such as AWS Tutorials and AWS Workshops. You can explore generative AI and agentic AI services playground and find the AWS Free Tier to try out AWS services free of charge up to specified limits for each service.

Choose the Toolbox page and discover the latest tools, programming language resources, and Open Source projects for AWS. The Toolbox has everything you need to get your project scaffolded and up and running.

To improve the build experience for builders, we plan to expand Builder Center’s built-in offerings such as creating dedicated groups and forums for collaborating on a particular topic, run workshops for hands-on labs, and various service playgrounds where builders can freely experiment with AWS services.

Supporting your builder journey
The new Learn section serves as your gateway to skill development, bringing together everything you need to expand your AWS expertise. Here, you can explore learning and training resources, workshops, gamified experiences, and more to make your journey of building on AWS both educational and engaging.

Choose the Topics page, where you can explore and discover more content. You can explore content by topics and tags. There is a featured and trending topics section that helps you to stay connected with what’s capturing the community’s attention right now.

Built-in localization for your spoken language
AWS Builder Center breaks down language barriers with comprehensive localization support. All content published in the Builder Center is automatically available in 16 languages, and user-generated content, such as posts, comments, or wishes, can be machine-translated on demand using Translate. So, you can collaborate with builders worldwide, sharing knowledge and experiences across language boundaries.

By default, all content will be displayed in based on the language that your browser is set to. But, you can override this by visiting the settings page and choosing the language that you want AWS Builder Center to use by default.

Sign up and build your profile now
AWS Builder Center gives you a more personalized and comprehensive way to showcase your AWS journey. Your unique profile comes with a custom URL and shareable QR code, making it straightforward to connect with others and share your presence in the AWS community.

All your posts, wishes, and meaningful interactions are organized within a centralized view so you can easily check them. In the Manage profile page, you can customize your profile, add specific interests and areas of expertise, helping you connect with builders who share your passions. Profile management is seamless: it synchronizes across all AWS services using AWS Builder ID, ensuring your identity remains consistent wherever you engage with AWS offerings.

Visit builder.aws.com, sign up with AWS Builder ID, and claim your unique alias to access all features, including content creation, Wishlist, and community engagement tools.

AWS Builder Center was designed to help you connect, learn, and build with fellow AWS builders, so enjoy your journey together!

— Channy & Matheus Guimaraes | @codingmatheus

Introducing Oracle Database@AWS for simplified Oracle Exadata migrations to the AWS Cloud

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-oracle-databaseaws-for-simplified-oracle-exadata-migrations-to-the-aws-cloud/

Today, we’re announcing the general availability of Oracle Database@AWS, a new offering for Oracle Exadata workloads, including Oracle Real Application Clusters (RAC) within AWS.

In the past 14 years, customers had the choice of self-managing Oracle database workloads in the cloud using Amazon Elastic Compute Cloud (Amazon EC2) or using fully managed Amazon Relational Database Service (Amazon RDS) for Oracle. Now, you have an additional option for your workloads that require Oracle RAC or Oracle Exadata for quicker and simpler migrations to the cloud. You also get a single invoice through AWS Marketplace, which counts towards AWS commitments and Oracle license benefits, including Bring Your Own License (BYOL) and discount programs such as Oracle Support Rewards.

With Oracle Database@AWS, you can migrate your Oracle Exadata workloads to Oracle Exadata Database Service on Dedicated Infrastructure or Oracle Autonomous Database on Dedicated Exadata Infrastructure within AWS with minimal changes. You can purchase, provision, and manage your Oracle Database@AWS deployments through familiar AWS tools and interfaces such as AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS APIs for applications running on AWS. The AWS APIs call the corresponding Oracle Cloud Infrastructure (OCI) APIs necessary to provision and manage the resources.

Since its preview last December, we’ve improved or added features to help run production workloads at general availability:

  • Regional expansion – You can now use Oracle Database@AWS in the U.S. East (N. Virginia) and U.S. West (Oregon) Regions today. We are also announcing plans to expand to 20 AWS Regions globally. This broader availability supports the diverse needs of our customers across various geographical areas so more enterprises can benefit from this option. You can choose from different Exadata system sizes to match your workload requirements in your AWS Region.
  • Zero-ETL and S3 backups – You can now benefit from zero-ETL integration with Amazon Redshift for analytics to remove the need to build and manage data pipelines for extract, transform, and load operations. With zero-ETL, you can unify your data on AWS without incurring cross network data transfer costs. We’re providing Amazon Simple Storage Service (Amazon S3) backups with up to eleven nines of data durability.
  • Autonomous VM cluster – You can now provision an Autonomous VM Cluster in addition to an Exadata VM cluster on the Exadata Dedicated Infrastructure. You can run Oracle Autonomous Database on Dedicated Exadata Infrastructure, a fully managed database environment using committed hardware and software resources.

Oracle Database@AWS also integrates with other AWS services such as Amazon Virtual Private Cloud (Amazon VPC) Lattice for configuring network paths to AWS services such as S3 and Redshift directly, AWS Identity and Access Management (IAM) for authentication and authorization, Amazon EventBridge for monitoring database lifecycle events, AWS CloudFormation for infrastructure automation, Amazon CloudWatch for collecting and monitoring metrics, and AWS CloudTrail for logging API operations.

Getting started with Oracle Database@AWS
Oracle Database@AWS supports two key services: Oracle Exadata Database Service on Dedicated Infrastructure and Oracle Autonomous Database on Dedicated Exadata Infrastructure within AWS data centers.

These services physically reside within an Availability Zone in an AWS Region and logically reside in an OCI region, enabling seamless integration with AWS services through high-speed, low-latency connections.

You create an ODB network, a private, isolated network that hosts Oracle Exadata VM Clusters within an Availability Zone. Then, you use ODB peering accessible to EC2 application servers running in a VPC. To learn more, visit How Oracle Database@AWS works in the AWS documentation.

Request a private offer in AWS Marketplace

To begin your journey with Oracle Database@AWS, visit the AWS console or request the AWS Marketplace private offer. Your AWS and Oracle sales team will receive your request, then contact you to find the best option for your workloads, and activate your account.

When you activate and get access to Oracle Database@AWS, you can use the Dashboard to create an ODB network, Exadata infrastructure, and Exadata VM cluster or Autonomous VM cluster, and ODB peering connection.

To learn more, visit the Onboarding to Oracle Database@AWS and AWS Marketplace buyer private offers in the AWS documentation.

Create an ODB network

An ODB network is a private isolated network that hosts OCI infrastructure on AWS. The ODB network maps directly to the network that exists within the OCI child site, thus serving as the means of communication between AWS and OCI.

In the Dashboard, choose Create ODB network, enter a network name, choose the Availability Zone, and specify a CIDR ranges for client connections established by applications and backup connections used for taking automated backups. You can also enter a name to use as a prefix to your domain fixed as oraclevcn.com. For example, if you enter myhost, the fully qualified domain name is myhost.oraclevcn.com.

Optionally, you can configure ODB network access to perform automated backups to Amazon S3 and zero-ETL for near real-time analytics and ML on your Oracle data using Amazon Redshift.

After you create your ODB network, update your VPC route tables of your EC2 application servers with the client connection CIDR in the ODB network. To learn more, visit ODB network, ODB peering, and Configuring VPC route tables for ODB peering in the AWS documentation.

Create Exadata infrastructure

The Oracle Exadata infrastructure is the underlying architecture of your database servers, storage servers, and networking that run your Oracle Exadata databases.

Choose Create Exadata infrastructure, enter a name, and use the default Availability Zone. In the next step, you can choose Exadata.X11M for the Exadata system model. You can also set a default of 2 or up to 32 database servers and 3 or up to 64 storage servers with 80 TB storage capacity per server.

Finally, you can configure system maintenance preferences, such as scheduling, patching mode, and OCI maintenance notification contacts. You can’t modify an infrastructure after you create it from the AWS console. But, you can navigate to the OCI console and modify it.

To delete an Exadata infrastructure, visit Deleting an Oracle Exadata infrastructure in Oracle Database@AWS in the AWS documentation.

Create an Exadata VM cluster or Autonomous VM cluster

You can create VM clusters on Exadata infrastructure and deploy multiple VM clusters with different Oracle Exadata infrastructures in the same ODB network.

Here are two types of VM clusters:

  • An Exadata VM cluster is a set of virtual machines that has a complete Oracle database installation that includes all features of Oracle Enterprise Edition.
  • An Autonomous VM cluster is a set of fully managed databases that automate key management tasks using AI/ML with no human intervention required.

Choose Create Exadata VM cluster, enter a VM cluster name and a time zone, choose Bring Your Own License (BYOL) or license included for license options. In the next step, you can choose your Exadata infrastructure, grid infrastructure version, and Exadata image version. For database servers, you can choose the CPU core count, memory, and local storage for each VM or accept the defaults.

In the next step, you can configure the connectivity setting by choosing your ODB network and entering a prefix for the VM cluster. You can enter a port number for TCP access to the single client access name (SCAN) listener. The default port is 1521 or you can enter a custom SCAN port in the range 1024–8999. For SSH key pairs, enter the public key portion of one or more key pairs used for SSH access to the VM cluster.

Then, you can choose diagnostics and tags, review your settings, and create a VM cluster. The creation process can take up to 6 hours, depending on the size of the VM cluster.

Create and manage an Oracle database

When the VM cluster is ready, you can create and manage your Oracle Exadata databases in the OCI console. Choose Manage in OCI in the details page of the Exadata VM cluster. You will be redirected to the OCI console.

When you create an Oracle Database in the OCI console, you can select Oracle Database 19c or 23ai. When enabling automatic backups for your provisioned databases, you can use an S3 bucket or OCI Object Storage in the OCI region. To learn more, visit Provision Oracle Exadata Database Service in Oracle Database@AWS in the OCI documentation.

Things to know
Here are a couple of things to know about Oracle Database@AWS:

  • Monitoring – You can monitor Oracle Database@AWS using Amazon CloudWatch metrics in the AWS/ODB namespaces for VM clusters, container databases, and pluggable databases. AWS CloudTrail captures all AWS API calls for Oracle Database@AWS as events. Using CloudTrail logs, you can determine the request that was made to Oracle Database@AWS, the IP address from which the request was made, when it was made, and additional details. To learn more, visit Monitoring Oracle Database@AWS.
  • Security – You can use IAM to assign permissions that determine who is allowed to manage Oracle Database@AWS resources and SSL/TLS encrypted connections to secure data. You can also use Amazon EventBridge for seamless event-driven database operations—all working together to maintain security standards while enabling efficient cloud operations. To learn more, visit Security in Oracle Database@AWS.
  • Compliance – Your compliance responsibility when using Oracle Database@AWS is determined by the sensitivity of your data, your company’s compliance objectives, and applicable laws and regulations. We provides the following compliances with Oracle Database@AWS: SOC 1, SOC 2, SOC 3, HIPAA, C5, CSA STAR Attest, CSA STAR Cert, HDS (France), ISO Series (ISO/IEC 9001, 20000-1, 27001, 27017, 27018, 27701, 22301), PCI DSS, and HITRUST. To learn more, visit Compliance validation for Oracle Database@AWS.
  • Support – Your AWS or Oracle sales account team can help you evaluate your current database infrastructure, determine how Oracle Database@AWS can best serve your organization’s requirements, and develop a tailored migration strategy and timeline. You can also get help from AWS Oracle Competency Partners specialized to architect, deploy, and manage Oracle-based workloads running in the AWS Cloud.

Now available and coming soon
Oracle Database@AWS is now available in the U.S. East (N. Virginia) and U.S. West (Oregon) Regions through the AWS Marketplace. Oracle Database@AWS pricing and any AWS Marketplace private offers are set by Oracle. You can see specific details around pricing on Oracle’s pricing page for the offering.

Oracle Database@AWS will expand to 20 more AWS Regions across the Americas, Europe, and Asia-Pacific including: US East (Ohio), US West (N. California), Asia Pacific (Hyderabad), Asia Pacific (Melbourne), Asia Pacific (Mumbai), Asia Pacific (Osaka), Asia Pacific (Seoul), Asia Pacific (Singapore), Asia Pacific (Sydney), Asia Pacific (Tokyo), Canada (Central), Europe (Frankfurt), Europe (Ireland), Europe (London), Europe (Milan), Europe (Paris), Europe (Spain), Europe (Stockholm), Europe (Zurich), and South America (São Paulo).

You can get started with Oracle Database@AWS with using AWS console. To learn more, visit the Oracle Database@AWS User Guide and OCI documentation and send feedback through your usual AWS Support contacts or OCI support.

— Channy

AWS Weekly Roundup: EC2 C8gn instances, Amazon Nova Canvas virtual try-on, and more (July 7, 2025)

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-bedrock-api-keys-amazon-nova-canvas-virtual-try-on-and-more-july-7-2025/

Every Monday we tell you about the best releases and blogs that caught our attention last week.

Before continuing with this AWS Weekly Roundup, I’d like to share that last month I moved with my family to San Francisco, California, to start a new role as Developer Advocate/SDE, GenAI.

This excites me because I’ll have the opportunity to connect with new communities in the Bay Area while tackling exciting new challenges. If you’re part of a community focused on building generative AI and agentics applications, or know of one, I’d love to connect. Let’s connect!

Last week’s launches
Here are the launches from last week:

  • New Amazon EC2 C8gn instances powered by AWS Graviton4 offering up to 600Gbps network bandwidth – Amazon Elastic Compute Cloud (Amazon EC2) C8gn instances are now generally available, powered by AWS Graviton4 processors and 6th generation AWS Nitro Cards. These network-optimized instances deliver up to 600 Gbps network bandwidth. This represents the highest bandwidth among EC2 network-optimized instances, with up to 192 vCPUs and 384 GiB memory. They provide 30% higher compute performance than C7gn instances and are ideal for network-intensive workloads like virtual appliances, data analytics, and cluster computing jobs.
  • Build the highest resilience apps with multi-Region strong consistency in Amazon DynamoDB global tables – Amazon DynamoDB global tables now supports multi-Region strong consistency (MRSC) for applications requiring zero Recovery Point Objective (RPO). This capability ensures applications can read the latest data from any Region during outages, addressing critical needs in payment processing and financial services. MRSC requires three AWS Regions configured as either three full replicas or two replicas plus a witness, providing the highest level of application resilience for mission-critical workloads.
  • Amazon Nova Canvas update: Virtual try-on and style options now available – Amazon Nova Canvas introduces virtual try-on capabilities that help you visualize how clothing looks on a person by combining two images, plus eight new pre-trained style options (3D animation, design sketch, vector illustration, graphic novel, etc.) for generating images with improved artistic consistency. Available in three AWS Regions, these features enhance AI-powered image generation capabilities for retailers and content creators seeking realistic product visualizations.
  • Amazon Q in Connect now supports 7 languages for proactive recommendations – Amazon Q in Connect, a generative AI-powered assistant for customer service, now provides proactive recommendations in seven languages: English, Spanish, French, Portuguese, Mandarin, Japanese, and Korean. The AI-powered customer service assistant detects customer intent during voice and chat interactions to help agents resolve issues quickly and accurately.
  • Amazon Aurora MySQL and Amazon RDS for MySQL integration with Amazon SageMaker is now available – This integration provides near real-time data availability for analytics. It automatically extracts MySQL data into lakehouses with Apache Iceberg compatibility. You can then access this data seamlessly through various analytics engines and machine learning tools.
  • Amazon Aurora DSQL is now available in additional AWS Regions – Amazon Aurora DSQL expands to Asia Pacific (Seoul) and now supports multi-Region clusters across Asia Pacific and European regions. This serverless, distributed SQL database offers unlimited scalability, highest availability, and zero infrastructure management with AWS Free Tier access.

Other AWS blog posts

  • Optimize RAG in production environments using Amazon SageMaker JumpStart and Amazon OpenSearch Service – Learn how to optimize Retrieval Augmented Generation (RAG) in production environments using Amazon SageMaker JumpStart and Amazon OpenSearch Service. This comprehensive guide demonstrates implementing RAG workflows with LangChain, covers OpenSearch optimization strategies, provides setup instructions, and explains benefits of combining these AWS services for scalable, cost-effective generative AI applications.v
  • Agentic GenAI App Using Bedrock, MCP servers on EKS – This post shows how to build a scalable AI chat application using Amazon Bedrock, Strands Agent, and Model Context Protocol (MCP) servers deployed on Amazon Elastic Kubernetes Service (Amazon EKS). The architecture combines agentic workflows with containerized microservices for intelligent, auto-scaling conversations with multiple foundation models.
  • Enforce table level access control on data lake tables using AWS Glue 5.0 with AWS Lake Formation – AWS Glue 5.0 introduces Full-Table Access (FTA) control for Apache Spark with AWS Lake Formation, providing table-level security without fine-grained access overhead. This feature supports native Spark SQL/DataFrames for Lake Formation tables. It enables read/write operations on Iceberg and Hive tables with improved performance and lower costs.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS re:Invent – Register now to get a head start on choosing your best learning path, booking travel and accommodations, and bringing your team to learn, connect, and have fun. Early-career professionals can apply for the All Builders Welcome Grant program, designed to remove financial barriers and create diverse pathways into cloud technology. Applications are now open and close on July 15, 2025.
  • AWS NY Summit – You can gain insights from Swami’s keynote featuring the latest cutting-edge AWS technologies in compute, storage, and generative AI. My News Blog team is also preparing some exciting news for you. If you’re unable to attend in person, you can still participate by registering for the global live stream. Also, save the date for these upcoming Summits in July and August near your city.
  • AWS Builders Online Series – If you’re based in one of the Asia Pacific time zones, join and learn fundamental AWS concepts, architectural best practices, and hands-on demonstrations to help you build, migrate, and deploy your workloads on AWS.
  • Join AWS Gen AI Lofts – Experience AWS Gen AI Lofts across San Francisco, Berlin, Dubai, Dublin, Bengaluru, Manchester, Paris, Tel Aviv, and additional locations – hands-on workshops, expert guidance, investor networking, and collaborative spaces designed to accelerate your generative AI startup journey.

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Eli

Amazon Nova Canvas update: Virtual try-on and style options now available

Post Syndicated from Matheus Guimaraes original https://aws.amazon.com/blogs/aws/amazon-nova-canvas-update-virtual-try-on-and-style-options-now-available/

Have you ever wished you could quickly visualize how a new outfit might look on you before making a purchase? Or how a piece of furniture would look in your living room? Today, we’re excited to introduce a new virtual try-on capability in Amazon Nova Canvas that makes this possible. In addition, we are adding eight new style options for improved style consistency for text-to-image based style prompting. These features expand Nova Canvas AI-powered image generation capabilities making it easier than ever to create realistic product visualizations and stylized images that can enhance the experience of your customers.

Let’s take a quick look at how you can start using these today.

Getting started
The first thing is to make sure that you have access to the Nova Canvas model through the usual means. Head to the Amazon Bedrock console, choose Model access and enable Amazon Nova Canvas for your account making sure that you select the appropriate regions for your workloads. If you already have access and have been using Nova Canvas, you can start using the new features immediately as they’re automatically available to you.

Virtual try-on
The first exciting new feature is virtual try-on. With this, you can upload two pictures and ask Amazon Nova Canvas to put them together with realistic results. These could be pictures of apparel, accessories, home furnishings, and any other products including clothing. For example, you can provide the picture of a human as the source image and the picture of a garment as the reference image, and Amazon Nova Canvas will create a new image with that same person wearing the garment. Let’s try this out!

My starting point is to select two images. I picked one of myself in a pose that I think would work well for a clothes swap and a picture of an AWS-branded hoodie.

Matheus and AWS-branded hoodie

Note that Nova Canvas accepts images containing a maximum of 4.1M pixels – the equivalent of 2,048 x 2,048 – so be sure to scale your images to fit these constraints if necessary. Also, if you’d like to run the Python code featured in this article, ensure you have Python 3.9 or later installed as well as the Python packages boto3 and pillow.

To apply the hoodie to my photo, I use the Amazon Bedrock Runtime invoke API. You can find full details on the request and response structures for this API in the Amazon Nova User Guide. The code is straightforward, requiring only a few inference parameters. I use the new taskType of "VIRTUAL_TRY_ON". I then specify the desired settings, including both the source image and reference image, using the virtualTryOnParams object to set a few required parameters. Note that both images must be converted to Base64 strings.

import base64


def load_image_as_base64(image_path): 
   """Helper function for preparing image data."""
   with open(image_path, "rb") as image_file:
      return base64.b64encode(image_file.read()).decode("utf-8")


inference_params = {
   "taskType": "VIRTUAL_TRY_ON",
   "virtualTryOnParams": {
      "sourceImage": load_image_as_base64("person.png"),
      "referenceImage": load_image_as_base64("aws-hoodie.jpg"),
      "maskType": "GARMENT",
      "garmentBasedMask": {"garmentClass": "UPPER_BODY"}
   }
}

Nova Canvas uses masking to manipulate images. This is a technique that allows AI image generation to focus on specific areas or regions of an image while preserving others, similar to using painter’s tape to protect areas you don’t want to paint.

You can use three different masking modes, which you can choose by setting maskType to the correct value. In this case, I’m using "GARMENT", which requires me to specify which part of the body I want to be masked. I’m using "UPPER_BODY" , but you can use others such as "LOWER_BODY", "FULL_BODY", or "FOOTWEAR" if you want to specifically target the feet. Refer to the documentation for a full list of options.

I then call the invoke API, passing in these inference arguments and saving the generated image to disk.

# Note: The inference_params variable from above is referenced below.

import base64
import io
import json

import boto3
from PIL import Image

# Create the Bedrock Runtime client.
bedrock = boto3.client(service_name="bedrock-runtime", region_name="us-east-1")

# Prepare the invocation payload.
body_json = json.dumps(inference_params, indent=2)

# Invoke Nova Canvas.
response = bedrock.invoke_model(
   body=body_json,
   modelId="amazon.nova-canvas-v1:0",
   accept="application/json",
   contentType="application/json"
)

# Extract the images from the response.
response_body_json = json.loads(response.get("body").read())
images = response_body_json.get("images", [])

# Check for errors.
if response_body_json.get("error"):
   print(response_body_json.get("error"))

# Decode each image from Base64 and save as a PNG file.
for index, image_base64 in enumerate(images):
   image_bytes = base64.b64decode(image_base64)
   image_buffer = io.BytesIO(image_bytes)
   image = Image.open(image_buffer)
   image.save(f"image_{index}.png")

I get a very exciting result!

Matheus wearing AWS-branded hoodie

And just like that, I’m the proud wearer of an AWS-branded hoodie!

In addition to the "GARMENT" mask type, you can also use the "PROMPT" or "IMAGE" masks. With "PROMPT", you also provide the source and reference images, however, you provide a natural language prompt to specify which part of the source image you’d like to be replaced. This is similar to how the "INPAINTING" and "OUTPAINTING" tasks work in Nova Canvas. If you want to use your own image mask, then you choose the "IMAGE" mask type and provide a black-and-white image to be used as mask, where black indicates the pixels that you want to be replaced on the source image, and white the ones you want to preserve.

This capability is specifically useful for retailers. They can use it to help their customers make better purchasing decisions by seeing how products look before buying.

Using style options
I’ve always wondered what I would look like as an anime superhero. Previously, I could use Nova Canvas to manipulate an image of myself, but I would have to rely on my good prompt engineering skills to get it right. Now, Nova Canvas comes with pre-trained styles that you can apply to your images to get high-quality results that follow the artistic style of your choice. There are eight available styles including 3D animated family film, design sketch, flat vector illustration, graphic novel, maximalism, midcentury retro, photorealism, and soft digital painting.

Applying them is as straightforward as passing in an extra parameter to the Nova Canvas API. Let’s try an example.

I want to generate an image of an AWS superhero using the 3D animated family film style. To do this, I specify a taskType of "TEXT_IMAGE" and a textToImageParams object containing two parameters: text and style. The text parameter contains the prompt describing the image I want to create which in this case is “a superhero in a yellow outfit with a big AWS logo and a cape.” The style parameter specifies one of the predefined style values. I’m using "3D_ANIMATED_FAMILY_FILM" here, but you can find the full list in the Nova Canvas User Guide.

inference_params = {
   "taskType": "TEXT_IMAGE",
   "textToImageParams": {
      "text": "a superhero in a yellow outfit with a big AWS logo and a cape.",
      "style": "3D_ANIMATED_FAMILY_FILM",
   },
   "imageGenerationConfig": {
      "width": 1280,
      "height": 720,
      "seed": 321
   }
}

Then, I call the invoke API just as I did in the previous example. (The code has been omitted here for brevity.) And the result? Well, I’ll let you judge for yourself, but I have to say I’m quite pleased with the AWS superhero wearing my favorite color following the 3D animated family film style exactly as I envisioned.

What’s really cool is that I can keep my code and prompt exactly the same and only change the value of the style attribute to generate an image in a completely different style. Let’s try this out. I set style to PHOTOREALISM.

inference_params = { 
   "taskType": "TEXT_IMAGE", 
   "textToImageParams": { 
      "text": "a superhero in a yellow outfit with a big AWS logo and a cape.",
      "style": "PHOTOREALISM",
   },
   "imageGenerationConfig": {
      "width": 1280,
      "height": 720,
      "seed": 7
   }
}

And the result is impressive! A photorealistic superhero exactly as I described, which is a far departure from the previous generated cartoon and all it took was changing one line of code.

Things to know
Availability – Virtual try-on and style options are available in Amazon Nova Canvas in the US East (N. Virginia), Asia Pacific (Tokyo), and Europe (Ireland). Current users of Amazon Nova Canvas can immediately use these capabilities without migrating to a new model.

Pricing – See the Amazon Bedrock pricing page for details on costs.

For a preview of virtual try-on of garments, you can visit nova.amazon.com where you can upload an image of a person and a garment to visualize different clothing combinations.

If you are ready to get started, please check out the Nova Canvas User Guide or visit the AWS Console.

Matheus Guimaraes | @codingmatheus

Build the highest resilience apps with multi-Region strong consistency in Amazon DynamoDB global tables

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/build-the-highest-resilience-apps-with-multi-region-strong-consistency-in-amazon-dynamodb-global-tables/

While tens of thousands of customers are successfully using Amazon DynamoDB global tables with eventual consistency, we’re seeing emerging needs for even stronger resilience. Many organizations find that the DynamoDB multi-Availability Zone architecture and eventually consistent global tables meet their requirements, but critical applications like payment processing systems and financial services demand more.

For these applications, customers require a zero Recovery Point Objective (RPO) during rare Region-wide events, meaning you can direct your app to read the latest data from any Region. Your multi-Region applications always need to access the same data regardless of location.

Starting today, you can use a new Amazon DynamoDB global tables capability that provides multi-Region strong consistency (MRSC), enabling zero RPO. This capability, first announced as a preview at AWS re:Invent 2024, simplifies building highly resilient global applications.

Here’s how you can enable MRSC starting with an existing empty DynamoDB table:

With MRSC, DynamoDB now offers you the highest level of resilience for your applications. If application processing is interrupted in a Region, you can redirect traffic to another Region containing a MRSC replica and know that you’ll be processing the latest data.

Getting started
Let me walk you through how you can use this new capability.

To start using MRSC, I need to create a global table from an existing DynamoDB table that doesn’t contain any data. I navigate to my existing table, select the Global tables tab and select Create replica.

The MRSC availability architecture requires three AWS Regions. I can configure MRSC with either three full replicas or with two replicas and a witness. A witness contains only replicated change data to provide the required availability without maintaining a full copy of my table data.

The following screenshot shows how I configure MRSC with two replicas and a witness. To configure MRSC with three full replicas instead, I can clear Configure Region 2 as Witness.

If I need to update my existing table programmatically, I can use the Amazon Q CLI to generate the required command with the following prompt:

> Hey Q! Update my existing DynamoDB table called "demo-mrsc" in us-east-1 with multi-Region strong consistency across us-east-2 with witness in us-west-2 Regions

Shortly after, Q CLI will respond back with following command:

> To update your DynamoDB table with multi-Region strong consistency, you'll need to use the update-table command with the appropriate parameters. Here's how you would do it:

aws dynamodb update-table \ 
    --table-name demo-mrsc \ 
    --replica-updates '[{"Create": {"RegionName": "us-east-2"}}]' \ 
    --global-table-witness-updates '[{"Create": {"RegionName": "us-west-2"}}]' \ 
    --multi-region-consistency STRONG \ 
    --region us-east-1

After it’s finished processing, I can check the status of my MRSC global table. I can see I have a witness configured for my DynamoDB global table. A witness reduces costs while still providing the resilience benefits of multi-Region strong consistency.

Then, in my application, I can use ConsistentRead to read data with strong consistency. Here’s a Python example:

import boto3

# Configure the DynamoDB client for your region
dynamodb = boto3.resource('dynamodb', region_name='us-east-2')
table = dynamodb.Table('demo-mrsc')

pk_id = "demo#test123"

# Read with strong consistency across regions
response = table.get_item(
    Key={
        'PK': pk_id
    },
    ConsistentRead=True
)

print(response)

For operations that require the strongest resilience, I can use ConsistentRead=True. For less critical operations where eventual consistency is acceptable, I can omit this parameter to improve performance and reduce costs.

Additional things to know
Here are a couple of things to note:

  • Availability – The Amazon DynamoDB multi-Region strong consistency capability is available in following AWS Regions: US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Osaka, Seoul, Tokyo), and Europe (Frankfurt, Ireland, London, Paris)
  • Pricing – Multi-Region strong consistency pricing follows the existing global tables pricing structure. DynamoDB recently reduced global tables pricing by up to 67 percent, making this highly resilient architecture more affordable than ever. Visit Amazon DynamoDB lowers pricing for on-demand throughput and global tables in the AWS Database Blog to learn more.

Learn more about how you can achieve the highest level of application resilience, enable your applications to be always available and always read the latest data regardless of the Region by visiting Amazon DynamoDB global tables.

Happy building!

— Donnie


New Amazon EC2 C8gn instances powered by AWS Graviton4 offering up to 600Gbps network bandwidth

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-c8gn-instances-powered-by-aws-graviton4-offering-up-to-600gbps-network-bandwidth/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) C8gn network optimized instances powered by AWS Graviton4 processors and the latest 6th generation AWS Nitro Card. EC2 C8gn instances deliver up to 600Gbps network bandwidth, the highest bandwidth among EC2 network optimized instances.

You can use C8gn instances to run the most demanding network intensive workloads, such as security and network virtual appliances (virtual firewalls, routers, load balancers, proxy servers, DDoS appliances), data analytics, and tightly-coupled cluster computing jobs.

EC2 C8gn instances specifications
C8gn instances provide up to 192 vCPUs and 384 GiB memory, and offer up to 30 percent higher compute performance compared Graviton3-based EC2 C7gn instances.

Here are the specs for C8gn instances:

Instance Name vCPUs Memory (GiB) Network Bandwidth (Gbps) EBS Bandwidth (Gbps)
c8gn.medium 1 2 Up to 25 Up to 10
c8gn.large 2 4 Up to 30 Up to 10
c8gn.xlarge 4 8 Up to 40 Up to 10
c8gn.2xlarge 8 16 Up to 50 Up to 10
c8gn.4xlarge 16 32 50 10
c8gn.8xlarge 32 64 100 20
c8gn.12xlarge 48 96 150 30
c8gn.16xlarge 64 128 200 40
c8gn.24xlarge 96 192 300 60
c8gn.metal-24xl 96 192 300 60
c8gn.48xlarge 192 384 600 60
c8gn.metal-48xl 192 384 600 60

You can launch C8gn instances through the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs.

If you’re using C7gn instances now, you will have straightforward experience migrating network intensive workloads to C8gn instances because the new instances offer similar vCPU and memory ratios. To learn more, check out the collection of Graviton resources to help you start migrating your applications to Graviton instance types.

You can also visit the Level up your compute with AWS Graviton page to begin your Graviton adoption journey.

Now available
Amazon EC2 C8gn instances are available today in US East (N. Virginia) and US West (Oregon) Regions. Two metal instance sizes are only available in US East (N. Virginia) Region. These instances can be purchased as On-Demand, Savings Plan, Spot instances, or as Dedicated instances and Dedicated hosts.

Give C8gn instances a try in the Amazon EC2 console. To learn more, refer to the Amazon EC2 C8g instance page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: Project Rainier, Amazon CloudWatch investigations, AWS MCP servers, and more (June 30, 2025)

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-project-rainier-amazon-cloudwatch-investigations-aws-mcp-servers-and-more-june-30-2025/

Every time I visit Seattle, the first thing that greets me at the airport is Mount Rainier. Did you know that the most innovative project at Amazon Web Services (AWS) is named after this mountain?

Project Rainier is a new project to create what is expected to be the world’s most powerful computer for training AI models across multiple data centers in the United Stages. Anthropic will develop the advanced versions of its Claude models with five times more computing power than its current largest training cluster.

The key technology powering Project Rainier is AWS custom-designed Trainium2 chips, which are specialized for the immense data processing required to train complex AI models. Thousands of these Trainium2 chips will be connected in a new type of Amazon EC2 UltraServer and EC2 UltraCluster architecture that allows ultra-fast communication and data sharing across the massive system.

Learn about the AWS vertical integration of Project Rainer, where it designs every component of the technology stack from chips to software, allows it to optimize the entire system for maximum efficiency and reliability.

Last week’s launches
Here are some launches that got my attention:

  • Amazon S3 access for Amazon FSx for OpenZFS – You can access and analyze your FSx for OpenZFS file data through Amazon S3 Access Points, enabling seamless integration with AWS AI/ML, and analytics services without moving your data out of the file system. You can treat your FSx for OpenZFS data as if it were stored in S3, making it accessible through the S3 API for various applications including Amazon Bedrock, Amazon SageMaker, AWS Glue, and other S3 based cloud-native applications.
  • Amazon S3 with sort and z-order compaction for Apache Iceberg tables – You can optimize query performance and reduce costs with new sort and z-order compaction. With S3 Tables, sort compaction automatically organizes data files based on defined column orders, while z-order compaction can be enabled through the maintenance API for efficient multicolumn queries.
  • Amazon CloudWatch investigations – You can accelerate your operational troubleshooting in AWS environments using the Amazon CloudWatch AI-powered investigation feature, which helps identify anomalies, surface related signals, and suggest remediation steps. This capability can be initiated through CloudWatch data widgets, multiple AWS consoles, CloudWatch alarm actions, or Amazon Q chat and enables team collaboration and integration with Slack and Microsoft Teams.
  • Amazon Bedrock Guardrails Standard tier – You can enhance your AI content safety measures using the new Standard tier. It offers improved content filtering and topic denial capabilities across up to 60 languages, better detection of variations including typos, and stronger protection against prompt attacks. This feature lets you configure safeguards to block harmful content, prevent model hallucinations, redact personally identifiable information (PII), and verify factual claims through automated reasoning checks.
  • Amazon Route 53 Resolver endpoints for private hosted zone – You can simplify DNS management across AWS and on-premises infrastructure using the new Route 53 DNS delegation feature for private hosted zone subdomains, which works with both inbound and outbound Resolver endpoints. You can delegate subdomain authority between your on-premises infrastructure and Route 53 Resolver cloud service using name server records, eliminating the need for complex conditional forwarding rules.
  • Amazon Q Developer CLI for Java transformation – You can automate and scale Java application upgrades using the new Amazon Q Developer Java transformation command line interface (CLI). This feature perform upgrades from Java versions 8, 11, 17, or 21 to versions 17 or 21 directly from the command line. This tool offers selective transformation options so you can choose specific steps from transformation plans and customize library upgrades.
  • New AWS IoT Device Management managed integrations – You can simplify Internet of Things (IoT) device management across multiple manufacturers and protocols using the new managed integrations feature, which provides a unified interface for controlling devices whether they connect directly, through hubs or third-party clouds. The feature includes pre-built cloud-to-cloud (C2C) connectors, device data model templates, and SDKs that support ZigBee, Z-Wave, and Wi-Fi protocols, while you can still create custom connectors and data models.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS? page.

Other AWS news
Various Model Context Protocol (MCP) servers for AWS services have been released. Here are some tutorials about MCP servers that you might find interesting:

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events:

  • AWS re:Invent – Register now to get a head start on choosing your best learning path, booking travel and accommodations, and bringing your team to learn, connect, and have fun. If you’re an early-career professional, you can apply to the All Builders Welcome Grant program, which is designed to remove financial barriers and create diverse pathways into cloud technology.
  • AWS NY Summits – You can gain insights from Swami’s keynote featuring the latest cutting-edge AWS technologies in compute, storage, and generative AI. My News Blog team is also preparing some exciting news for you. If you’re unable to attend in person, you can still participate by registering for the global live stream. Also, save the date for these upcoming Summits in July and August near your city.
  • AWS Builders Online Series – If you’re based in one of the Asia Pacific time zones, join and learn fundamental AWS concepts, architectural best practices, and hands-on demonstrations to help you build, migrate, and deploy your workloads on AWS.

You can browse all upcoming in-person and virtual events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Channy

Amazon FSx for OpenZFS now supports Amazon S3 access without any data movement

Post Syndicated from Elizabeth Fuentes original https://aws.amazon.com/blogs/aws/amazon-fsx-for-openzfs-now-supports-amazon-s3-access-without-any-data-movement/

Starting today, you can attach Amazon S3 Access Points to your Amazon FSx for OpenZFS file systems to access your file data as if it were in Amazon Simple Storage Service (Amazon S3). With this new capability, your data in FSx for OpenZFS is accessible for use with a broad range of Amazon Web Services (AWS) services and applications for artificial intelligence, machine learning (ML), and analytics that work with S3. Your file data continues to reside in your FSx for OpenZFS file system.

Organizations store hundreds of exabytes of file data on premises and want to move this data to AWS for greater agility, reliability, security, scalability, and reduced costs. Once their file data is in AWS, organizations often want to do even more with it. For example, they want to use their enterprise data to augment generative AI applications and build and train machine learning models with the broad spectrum of AWS generative AI and machine learning services. They also want the flexibility to use their file data with new AWS applications. However, many AWS data analytics services and applications are built to work with data stored in Amazon S3 as data lakes. After migration, they can use tools that work with Amazon S3 as their data source. Previously, this required data pipelines to copy data between Amazon FSx for OpenZFS file systems and Amazon S3 buckets.

Amazon S3 Access Points attached to FSx for OpenZFS file systems remove data movement and copying requirements by maintaining unified access through both file protocols and Amazon S3 API operations. You can read and write file data using S3 object operations including GetObject, PutObject, and ListObjectsV2. You can attach hundreds of access points to a file system, with each S3 access point configured with application-specific permissions. These access points support the same granular permissions controls as S3 access points that attach to S3 buckets, including AWS Identity and Access Management (IAM) access point policies, Block Public Access, and network origin controls such as restricting access to your Virtual Private Cloud (VPC). Because your data continues to reside in your FSx for OpenZFS file system, you continue to access your data using Network File System (NFS) and benefit from existing data management capabilities.

You can use your file data in Amazon FSx for OpenZFS file systems to power generative AI applications with Amazon Bedrock for Retrieval Augmented Generation (RAG) workflows, train ML models with Amazon SageMaker, and run analytics or business intelligence (BI) with Amazon Athena and AWS Glue as if the data were in S3, using the S3 API. You can also generate insights using open source tools such as Apache Spark and Apache Hive, without moving or refactoring your data.

To get started
You can create and attach an S3 Access Point to your Amazon FSx for OpenZFS file system using the Amazon FSx console, the AWS Command Line Interface (AWS CLI), or the AWS SDK.

To start, you can follow the steps in the Amazon FSx for OpenZFS file system documentation page to create the file system, then, using the Amazon FSx console, go to Actions and select Create S3 access point. Leave the standard configuration and then create.

To monitor the creation progress, you can go to the Amazon FSx console.

Once available, choose the name of the new S3 access point and review the access point summary. This summary includes an automatically generated alias that works anywhere you would normally use S3 bucket names.

Using the bucket-style alias, you can access the FSx data directly through S3 API operations.

  • List objects using the ListObjectsV2 API

  • Get files using the GetObject API

  • Write data using the PutObject API

The data continues to be accessible via NFS.

Beyond accessing your FSx data through the S3 API, you can work with your data using the broad range of AI, ML, and analytics services that work with data in S3. For example, I built an Amazon Bedrock Knowledge Base using PDFs containing airline customer service information from my travel support application repository, WhatsApp-Powered RAG Travel Support Agent: Elevating Customer Experience with PostgreSQL Knowledge Retrieval, as the data source.

To create the Amazon Bedrock Knowledge Base, I followed the connection steps in Connect to Amazon S3 for your knowledge base user guide. I chose Amazon S3 as the data source, entered my S3 access point alias as the S3 source, then configured and created the knowledge base.

Once the knowledge base is synchronized, I can see all documents and the Document source as S3.

Finally, I ran queries against the knowledge base and verified that it successfully used the file data from my Amazon FSx for OpenZFS file system to provide contextual answers, demonstrating seamless integration without data movement.

Things to know
Integration and access control – Amazon S3 Access Points for Amazon FSx for OpenZFS file systems support standard S3 API operations (such as GetObject, ListObjectsV2, PutObject) through the S3 endpoint, with granular access controls through AWS Identity and Access Management (IAM) permissions and file system user authentication. Your S3 Access Point includes an automatically generated access point alias for data access using S3 bucket names, and public access is blocked by default for Amazon FSx resources.

Data management – Your data stays in your Amazon FSx for OpenZFS file system while becoming accessible as if it were in Amazon S3, eliminating the need for data movement or copies, with file data remaining accessible through NFS file protocols.

Performance – Amazon S3 Access Points for Amazon FSx for OpenZFS file systems deliver first-byte latency in the tens of milliseconds range, consistent with S3 bucket access. Performance scales with your Amazon FSx file system’s provisioned throughput, with maximum throughput determined by your underlying FSx file system configuration.

Pricing – You’re billed by Amazon S3 for the requests and data transfer costs through your S3 Access Point, in addition to your standard Amazon FSx charges. Learn more on the Amazon FSx for OpenZFS pricing page.

You can get started today using the Amazon FSx console, AWS CLI, or AWS SDK to attach Amazon S3 Access Points to your Amazon FSx for OpenZFS file systems. The feature is available in the following AWS Regions: US East (N. Virginia, Ohio), US West (Oregon), Europe (Frankfurt, Ireland, Stockholm), and Asia Pacific (Hong Kong, Singapore, Sydney, Tokyo).

— Eli

New: Improve Apache Iceberg query performance in Amazon S3 with sort and z-order compaction

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/new-improve-apache-iceberg-query-performance-in-amazon-s3-with-sort-and-z-order-compaction/

You can now use sort and z-order compaction to improve Apache Iceberg query performance in Amazon S3 Tables and general purpose S3 buckets.

You typically use Iceberg to manage large-scale analytical datasets in Amazon Simple Storage Service (Amazon S3) with AWS Glue Data Catalog or with S3 Tables. Iceberg tables support use cases such as concurrent streaming and batch ingestion, schema evolution, and time travel. When working with high-ingest or frequently updated datasets, data lakes can accumulate many small files that impact the cost and performance of your queries. You’ve shared that optimizing Iceberg data layout is operationally complex and often requires developing and maintaining custom pipelines. Although the default binpack strategy with managed compaction provides notable performance improvements, introducing sort and z-order compaction options for both S3 and S3 Tables delivers even greater gains for queries filtering across one or more dimensions.

Two new compaction strategies: Sort and z-order
To help organize your data more efficiently, Amazon S3 now supports two new compaction strategies: sort and z-order, in addition to the default binpack compaction. These advanced strategies are available for both fully managed S3 Tables and Iceberg tables in general purpose S3 buckets through AWS Glue Data Catalog optimizations.

Sort compaction organizes files based on a user-defined column order. When your tables have a defined sort order, S3 Tables compaction will now use it to cluster similar values together during the compaction process. This improves the efficiency of query execution by reducing the number of files scanned. For example, if your table is organized by sort compaction along state and zip_code, queries that filter on those columns will scan fewer files, improving latency and reducing query engine cost.

Z-order compaction goes a step further by enabling efficient file pruning across multiple dimensions. It interleaves the binary representation of values from multiple columns into a single scalar that can be sorted, making this strategy particularly useful for spatial or multidimensional queries. For example, if your workloads include queries that simultaneously filter by pickup_location, dropoff_location, and fare_amount, z-order compaction can reduce the total number of files scanned compared to traditional sort-based layouts.

S3 Tables use your Iceberg table metadata to determine the current sort order. If a table has a defined sort order, no additional configuration is needed to activate sort compaction—it’s automatically applied during ongoing maintenance. To use z-order, you need to update the table maintenance configuration using the S3 Tables API and set the strategy to z-order. For Iceberg tables in general purpose S3 buckets, you can configure AWS Glue Data Catalog to use sort or z-order compaction during optimization by updating the compaction settings.

Only new data written after enabling sort or z-order will be affected. Existing compacted files will remain unchanged unless you explicitly rewrite them by increasing the target file size in table maintenance settings or rewriting data using standard Iceberg tools. This behavior is designed to give you control over when and how much data is reorganized, balancing cost and performance.

Let’s see it in action
I’ll walk you through a simplified example using Apache Spark and the AWS Command Line Interface (AWS CLI). I have a Spark cluster installed and an S3 table bucket. I have a table named testtable in a testnamespace. I temporarily disabled compaction, the time for me to add data into the table.

After adding data, I check the file structure of the table.

spark.sql("""
  SELECT 
    substring_index(file_path, '/', -1) as file_name,
    record_count,
    file_size_in_bytes,
    CAST(UNHEX(hex(lower_bounds[2])) AS STRING) as lower_bound_name,
    CAST(UNHEX(hex(upper_bounds[2])) AS STRING) as upper_bound_name
  FROM ice_catalog.testnamespace.testtable.files
  ORDER BY file_name
""").show(20, false)
+--------------------------------------------------------------+------------+------------------+----------------+----------------+
|file_name                                                     |record_count|file_size_in_bytes|lower_bound_name|upper_bound_name|
+--------------------------------------------------------------+------------+------------------+----------------+----------------+
|00000-0-66a9c843-5a5c-407f-8da4-4da91c7f6ae2-0-00001.parquet  |1           |837               |Quinn           |Quinn           |
|00000-1-b7fa2021-7f75-4aaf-9a24-9bdbb5dc08c9-0-00001.parquet  |1           |824               |Tom             |Tom             |
|00000-10-00a96923-a8f4-41ba-a683-576490518561-0-00001.parquet |1           |838               |Ilene           |Ilene           |
|00000-104-2db9509d-245c-44d6-9055-8e97d4e44b01-0-00001.parquet|1000000     |4031668           |Anjali          |Tom             |
|00000-11-27f76097-28b2-42bc-b746-4359df83d8a1-0-00001.parquet |1           |838               |Henry           |Henry           |
|00000-114-6ff661ca-ba93-4238-8eab-7c5259c9ca08-0-00001.parquet|1000000     |4031788           |Anjali          |Tom             |
|00000-12-fd6798c0-9b5b-424f-af70-11775bf2a452-0-00001.parquet |1           |852               |Georgie         |Georgie         |
|00000-124-76090ac6-ae6b-4f4e-9284-b8a09f849360-0-00001.parquet|1000000     |4031740           |Anjali          |Tom             |
|00000-13-cb0dd5d0-4e28-47f5-9cc3-b8d2a71f5292-0-00001.parquet |1           |845               |Olivia          |Olivia          |
|00000-134-bf6ea649-7a0b-4833-8448-60faa5ebfdcd-0-00001.parquet|1000000     |4031718           |Anjali          |Tom             |
|00000-14-c7a02039-fc93-42e3-87b4-2dd5676d5b09-0-00001.parquet |1           |838               |Sarah           |Sarah           |
|00000-144-9b6d00c0-d4cf-4835-8286-ebfe2401e47a-0-00001.parquet|1000000     |4031663           |Anjali          |Tom             |
|00000-15-8138298d-923b-44f7-9bd6-90d9c0e9e4ed-0-00001.parquet |1           |831               |Brad            |Brad            |
|00000-155-9dea2d4f-fc98-418d-a504-6226eb0a5135-0-00001.parquet|1000000     |4031676           |Anjali          |Tom             |
|00000-16-ed37cf2d-4306-4036-98de-727c1fe4e0f9-0-00001.parquet |1           |830               |Brad            |Brad            |
|00000-166-b67929dc-f9c1-4579-b955-0d6ef6c604b2-0-00001.parquet|1000000     |4031729           |Anjali          |Tom             |
|00000-17-1011820e-ee25-4f7a-bd73-2843fb1c3150-0-00001.parquet |1           |830               |Noah            |Noah            |
|00000-177-14a9db71-56bb-4325-93b6-737136f5118d-0-00001.parquet|1000000     |4031778           |Anjali          |Tom             |
|00000-18-89cbb849-876a-441a-9ab0-8535b05cd222-0-00001.parquet |1           |838               |David           |David           |
|00000-188-6dc3dcca-ddc0-405e-aa0f-7de8637f993b-0-00001.parquet|1000000     |4031727           |Anjali          |Tom             |
+--------------------------------------------------------------+------------+------------------+----------------+----------------+
only showing top 20 rows

I observe the table is made of multiple small files and that the upper and lower bounds for the new files have overlap–the data is certainly unsorted.

I set the table sort order.

spark.sql("ALTER TABLE ice_catalog.testnamespace.testtable WRITE ORDERED BY name ASC")

I enable table compaction (it’s enabled by default; I disabled it at the start of this demo)

aws s3tables put-table-maintenance-configuration --table-bucket-arn ${S3TABLE_BUCKET_ARN} --namespace testnamespace --name testtable --type icebergCompaction --value "status=enabled,settings={icebergCompaction={strategy=sort}}"

Then, I wait for the next compaction job to trigger. These run throughout the day, when there are enough small files. I can check the compaction status with the following command.

aws s3tables get-table-maintenance-job-status --table-bucket-arn ${S3TABLE_BUCKET_ARN} --namespace testnamespace --name testtable

When the compaction is done, I inspect the files that make up my table one more time. I see that the data was compacted to two files, and the upper and lower bounds show that the data was sorted across these two files.

spark.sql("""
  SELECT 
    substring_index(file_path, '/', -1) as file_name,
    record_count,
    file_size_in_bytes,
    CAST(UNHEX(hex(lower_bounds[2])) AS STRING) as lower_bound_name,
    CAST(UNHEX(hex(upper_bounds[2])) AS STRING) as upper_bound_name
  FROM ice_catalog.testnamespace.testtable.files
  ORDER BY file_name
""").show(20, false)
+------------------------------------------------------------+------------+------------------+----------------+----------------+
|file_name                                                   |record_count|file_size_in_bytes|lower_bound_name|upper_bound_name|
+------------------------------------------------------------+------------+------------------+----------------+----------------+
|00000-4-51c7a4a8-194b-45c5-a815-a8c0e16e2115-0-00001.parquet|13195713    |50034921          |Anjali          |Kelly           |
|00001-5-51c7a4a8-194b-45c5-a815-a8c0e16e2115-0-00001.parquet|10804307    |40964156          |Liza            |Tom             |
+------------------------------------------------------------+------------+------------------+----------------+----------------+

There are fewer files, they have larger sizes, and there is a better clustering across the specified sort column.

To use z-order, I follow the same steps, but I set strategy=z-order in the maintenance configuration.

Regional availability
Sort and z-order compaction are now available in all AWS Regions where Amazon S3 Tables are supported and for general purpose S3 buckets where optimization with AWS Glue Data Catalog is available. There is no additional charge for S3 Tables beyond existing usage and maintenance fees. For Data Catalog optimizations, compute charges apply during compaction.

With these changes, queries that filter on the sort or z-order columns benefit from faster scan times and reduced engine costs. In my experience, depending on my data layout and query patterns, I observed performance improvements of threefold or more when switching from binpack to sort or z-order. Tell us how much your gains are on your actual data.

To learn more, visit the Amazon S3 Tables product page or review the S3 Tables maintenance documentation. You can also start testing the new strategies on your own tables today using the S3 Tables API or AWS Glue optimizations.

— seb

AWS Weekly Roundup: re:Inforce re:Cap, Valkey GLIDE 2.0, Avro and Protobuf or MCP Servers on Lambda, and more (June 23, 2025)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-reinforce-recap-valkey-glide-2-0-avro-and-protobuf-or-mcp-servers-on-lambda-and-more-june-23-2025/

Last week’s hallmark event was the security-focused AWS re:Inforce conference.


AWS re:Inforce 2025

AWS re:Inforce 2025

Now a tradition, the blog team wrote a re:Cap post to summarize the announcements and link to some of the top blog posts.

To further summarize, several new security innovations were announced, including enhanced IAM Access Analyzer capabilities, MFA enforcement for root users, and threat intelligence integration with AWS Network Firewall. Other notable updates include exportable public SSL/TLS certificates from AWS Certificate Manager, a simplified AWS WAF console experience, and a new AWS Shield feature for proactive network security (in preview). Additionally, AWS Security Hub has been enhanced for risk prioritization (Preview), and Amazon GuardDuty now supports Amazon EKS clusters.

But my favorite announcement came from the Amazon Verified Permissions team. They released an open source package for Express.js, enabling developers to implement external fine-grained authorization for web application APIs. This simplifies authorization integration, reducing code complexity and improving application security.

The team also published a blog post that outlines how to create a Verified Permissions policy store, add Cedar and Verified Permissions authorisation middleware to your app, create and deploy a Cedar schema, and create and deploy Cedar policies. The Cedar schema is generated from an OpenAPI specification and formatted for use with the AWS Command Line Interface (CLI).

Let’s look at last week’s other new announcements.

Last week’s launches
Apart from re:Inforce, here are the launches that got my attention.

Kafka customers use Avro and Protobuf formats for efficient data storage, fast serialization and deserialization, schema evolution support, and interoperability between different programming languages. They utilize schema registries to manage, evolve, and validate schemas before data enters processing pipelines. Previously, you were required to write custom code within your Lambda function to validate, deserialize, and filter events when using these data formats. With this launch, Lambda natively supports Avro and Protobuf, as well as integration with GSR, CCSR, and SCSR. This enables you to process your Kafka events using these data formats without writing custom code. Additionally, you can optimize costs through event filtering to prevent unnecessary function invocations.

  • Amazon S3 Express One Zone now supports atomic renaming of objects with a single API call – The RenameObject API simplifies data management in S3 directory buckets by transforming a multi-step rename operation into a single API call. This means you can now rename objects in S3 Express One Zone by specifying an existing object’s name as the source and the new name as the destination within the same S3 directory bucket. With no data movement involved, this capability accelerates applications like log file management, media processing, and data analytics, while also lowering costs. For instance, renaming a 1-terabyte log file can now complete in milliseconds, instead of hours, significantly accelerating applications and reducing costs.
  • Valkey introduces GLIDE 2.0 with support for Go, OpenTelemetry, and pipeline batching – AWS, in partnership with Google and the Valkey community, announces the general availability of General Language Independent Driver for the Enterprise (GLIDE) 2.0. This is the latest release of one of AWS’s official open-source Valkey client libraries. Valkey, the most permissive open-source alternative to Redis, is stewarded by the Linux Foundation and will always remain open-source. Valkey GLIDE is a reliable, high-performance, multi-language client that supports all Valkey commands

GLIDE 2.0 introduces new capabilities that expand developer support, improve observability, and optimise performance for high-throughput workloads. Valkey GLIDE 2.0 extends its multi-language support to Go (contributed by Google), joining Java, Python, and Node.js to provide a consistent, fully compatible API experience across all four languages. More language support is on the way. With this release, Valkey GLIDE now supports OpenTelemetry, an open-source, vendor-neutral framework that enables developers to generate, collect, and export telemetry data and critical client-side performance insights. Additionally, GLIDE 2.0 introduces batching capabilities, reducing network overhead and latency for high-frequency use cases by allowing multiple commands to be grouped and executed as a single operation.

You can discover more about Valkey GLIDE in this recent episode of the AWS Developers Podcast: Inside Valkey GLIDE: building a next-gen Valkey client library with Rust.

Podcast episode on Valkey Glide

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

Some other reading
My Belgian compatriot Alexis has written the first article of a two-part series explaining how to develop an MCP Tool server with a streamable HTTP transport and deploy it on Lambda and API Gateway. This is a must-read for anyone implementing MCP servers on AWS. I’m eagerly looking forward to the second part, where Alexis will discuss authentication and authorization for remote MCP servers.

Other AWS events
Check your calendar and sign up for upcoming AWS events.

AWS GenAI Lofts are collaborative spaces and immersive experiences that showcase AWS expertise in cloud computing and AI. They provide startups and developers with hands-on access to AI products and services, exclusive sessions with industry leaders, and valuable networking opportunities with investors and peers. Find a GenAI Loft location near you and don’t forget to register.

AWS Summits are free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Japan (this week June 25 – 26), Online in India (June 26), New-York City (July 16).

Save the date for these upcoming Summits in July and August: Taipei (July 29), Jakarta (August 7), Mexico (August 8), São Paulo (August 13), and Johannesburg (August 20) (and more to come in September and October).

Browse all upcoming AWS led in-person and virtual events here.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— seb

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

AWS re:Inforce roundup 2025: top announcements

Post Syndicated from AWS News Blog Team original https://aws.amazon.com/blogs/aws/aws-reinforce-roundup-2025-top-announcements/

At AWS re:Inforce 2025 (June 16-18, Philadelphia), AWS Vice President and Chief Information Security Officer Amy Herzog delivered the keynote address, announcing new security innovations. Throughout the event, AWS announced additional security capabilities focused on simplifying security at scale and enabling organizations to build more resilient applications in the cloud. Below is a comprehensive roundup of the major security launches and updates announced at this year’s conference.

Verify internal access to critical AWS resources with new IAM Access Analyzer capabilities
A new capability in AWS Identity and Access Management Access Analyzer helps security teams verify which principals within their AWS organization have access to critical resources like S3 buckets, DynamoDB tables, and RDS snapshots by using automated reasoning to evaluate multiple policies and provide findings through a unified dashboard.

AWS IAM now enforces MFA for root users across all account types
The new Multi-Factor Authentication enforcement prevents over 99% of password-related attacks. You can use a range of supported IAM MFA methods, including FIDO-certified security keys to harden access to your AWS accounts. AWS supports FIDO2 passkeys for a user-friendly MFA implementation and allows you to register up to 8 MFA devices per root and IAM user.

Improve your security posture using Amazon threat intelligence on AWS Network Firewall
This new Network Firewall managed rule group offers protection against active threats relevant to workloads in AWS. The feature uses the Amazon threat intelligence system MadPot to continuously track attack infrastructure, including malware hosting URLs, botnet command and control servers, and crypto mining pools, identifying indicators of compromise (IOCs) for active threats.

AWS Certificate Manager introduces exportable public SSL/TLS certificates to use anywhere
You can now use AWS Certificate Manager to issue exportable public certificates for your AWS, hybrid, or multicloud workloads that require secure TLS traffic termination.

AWS WAF simplified console experience
The new AWS WAF console experience reduces security configuration steps by up to 80% through pre-configured protection packs. Security teams can quickly implement comprehensive protection for specific application types, with consolidated security metrics and customizable controls through an intuitive interface.

Amazon CloudFront simplifies web application delivery and security with new user-friendly interface
Try the simplified console experience with Amazon CloudFront to accelerate and secure web applications within a few clicks by automating TLS certificate provisioning, DNS configuration, and security settings through an integrated interface with AWS WAF’s enhanced Rule Packs.

New AWS Shield feature discovers network security issues before they can be exploited (Preview)
Shield network security posture management automatically discovers and analyzes network resources across AWS accounts, prioritizes security risks based on AWS best practices, and provides actionable remediation recommendations to protect applications against threats like SQL injections and DDoS attacks.

Unify your security with the new AWS Security Hub for risk prioritization and response at scale (Preview)
AWS Security Hub has been enhanced to transform security signals into actionable insights, helping security teams prioritize and respond to critical issues at scale. This unified solution provides comprehensive visibility across your cloud environment while reducing the complexity of managing multiple security tools.

Amazon GuardDuty expands Extended Threat Detection coverage to Amazon EKS clusters
Amazon GuardDuty Extended Threat Detection now supports Amazon EKS clusters, helping you detect sophisticated multistage attacks by correlating security signals across Kubernetes audit logs, runtime behaviors, and AWS API activities. This enhancement automatically identifies critical attack sequences that might otherwise go unnoticed, enabling faster response to threats.

New categories for the AWS MSSP Competency
The AWS MSSP Competency (previously AWS Level 1 MSSP Competency) now includes new categories covering infrastructure security, workload security, application security, data protection, identity and access management, incident response, and cyber recovery. Partners provide 24/7 monitoring and incident response through dedicated Security Operations Centers.

Secure your Express application APIs in minutes with Amazon Verified Permissions
Amazon Verified Permissions announced the release of the verified-permissions-express-toolkit, an open-source package that allows developers to implement authorization for Express web application APIs in minutes using Amazon Verified Permissions.

Beyond compute: Shifting vulnerability detection left with Amazon Inspector code security
Amazon Inspector code security capabilities are now generally available, helping you secure applications before production by rapidly identifying and prioritizing security vulnerabilities and misconfigurations across application source code, dependencies, and infrastructure as code (IaC).

AWS Backup adds new Multi-party approval for logically air-gapped vaults
Multi-party approval for AWS Backup logically air-gapped vaults enables you to recover your backup data even when your AWS account is compromised, by leveraging authorization from a designated approval team of trusted individuals who can enable vault sharing with a recovery account.

Amazon GuardDuty expands Extended Threat Detection coverage to Amazon EKS clusters

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/amazon-guardduty-expands-extended-threat-detection-coverage-to-amazon-eks-clusters/

Today, I’m happy to announce Amazon GuardDuty Extended Threat Detection with expanded coverage for Amazon Elastic Kubernetes Service (Amazon EKS), building upon the capabilities we introduced in our AWS re:Invent 2024 announcement of Amazon GuardDuty Extended Threat Detection: AI/ML attack sequence identification for enhanced cloud security.

Security teams managing Kubernetes workloads often struggle to detect sophisticated multistage attacks that target containerized applications. These attacks can involve container exploitation, privilege escalation, and unauthorized movement within Amazon EKS clusters. Traditional monitoring approaches might detect individual suspicious events, but often miss the broader attack pattern that spans across these different data sources and time periods.

GuardDuty Extended Threat Detection introduces a new critical severity finding type, which automatically correlates security signals across Amazon EKS audit logs, runtime behaviors of processes associated with EKS clusters, malware execution in EKS clusters, and AWS API activity to identify sophisticated attack patterns that might otherwise go unnoticed. For example, GuardDuty can now detect attack sequences in which a threat actor exploits a container application, obtains privileged service account tokens, and then uses these elevated privileges to access sensitive Kubernetes secrets or AWS resources.

This new capability uses GuardDuty correlation algorithms to observe and identify sequences of actions that indicate potential compromise. It evaluates findings across protection plans and other signal sources to identify common and emerging attack patterns. For each attack sequence detected, GuardDuty provides comprehensive details, including potentially impacted resources, timeline of events, actors involved, and indicators used to detect the sequence. The findings also map observed activities to MITRE ATT&CK® tactics and techniques and remediation recommendations based on AWS best practices, helping security teams understand the nature of the threat.

To enable Extended Threat Detection for EKS, you need at least one of these features enabled: EKS Protection or Runtime Monitoring. For maximum detection coverage, we recommend enabling both to enhance detection capabilities. EKS Protection monitors control plane activities through audit logs, and Runtime Monitoring observes behaviors within containers. Together, they create a complete view of your EKS clusters, enabling GuardDuty to detect complex attack patterns.

How it works
To use the new Amazon GuardDuty Extended Threat Detection for EKS clusters, go to the GuardDuty console to enable EKS Protection in your account. From the Region selector in the upper-right corner, select the Region where you want to enable EKS Protection. In the navigation pane, choose EKS Protection. On the EKS Protection page, review the current status and choose Enable. Select Confirm to save your selection.

After it’s enabled, GuardDuty immediately starts monitoring EKS audit logs from your EKS clusters without requiring any additional configuration. GuardDuty consumes these audit logs directly from the EKS control plane through an independent stream, which doesn’t affect any existing logging configurations. For multi-account environments, only the delegated GuardDuty administrator account can enable or disable EKS Protection for member accounts and configure auto-enable settings for new accounts joining the organization.

To enable Runtime Monitoring, choose Runtime Monitoring in the navigation pane. Under the Configuration tab, choose Enable to enable Runtime Monitoring for your account.

Now, you can view from the Summary dashboard the attack sequences and critical findings specifically related to Kubernetes cluster compromise. You can observe that GuardDuty identifies complex attack patterns in Kubernetes environments, such as credential compromise events and suspicious activities within EKS clusters. The visual representation of findings by severity, resource impact, and attack types gives you a holistic view of your Amazon EKS security posture. This means you can prioritize the most critical threats to your containerized workloads.

The Finding details page provides visibility into complex attack sequences targeting EKS clusters, helping you understand the full scope of potential compromises. GuardDuty correlates signals into a timeline, mapping observed behaviors to MITRE ATT&CK® tactics and techniques such as account manipulation, resource hijacking, and privilege escalation. This granular level of insight reveals exactly how attackers progress through your Amazon EKS environment. It identifies affected resources like EKS workloads and service accounts. The detailed breakdown of indicators, actors, and endpoints provides you with actionable context to understand attack patterns, determine impact, and prioritize remediation efforts. By consolidating these security insights into a cohesive view, you can quickly assess the severity of Amazon EKS security incidents, reduce investigation time, and implement targeted countermeasures to protect your containerized applications.

The Resources section of the Finding details page shows context about the specific assets affected during an attack sequence. This unified resource list provides you with visibility into the exact scope of the compromise—from the initial access to the targeted Kubernetes components. Because GuardDuty includes detailed attributes such as resource types, identifiers, creation dates, and namespace information, you can rapidly assess which components of your containerized infrastructure require immediate attention. This focused approach eliminates guesswork during incident response, so you can prioritize remediation efforts on the most critical affected resources and minimize the potential blast radius of Amazon EKS targeted attacks.

Now available
Amazon GuardDuty Extended Threat Detection with expanded coverage for Amazon EKS clusters provides comprehensive security monitoring across your Kubernetes environment. You can use this capability to detect sophisticated multistage attacks by correlating events across different data sources, identifying attack sequences that traditional monitoring might miss.

To start using this expanded coverage, enable EKS Protection in your GuardDuty settings and consider adding Runtime Monitoring for enhanced detection capabilities.

For more information about this new capability, refer to the Amazon GuardDuty Documentation.

— Esra

Unify your security with the new AWS Security Hub for risk prioritization and response at scale (Preview)

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/unify-your-security-with-the-new-aws-security-hub-for-risk-prioritization-and-response-at-scale-preview/

AWS Security Hub has been a central place for you to view and aggregate security alerts and compliance status across Amazon Web Services (AWS) accounts. Today, we are announcing the preview release of the new AWS Security Hub which offers additional correlation, contextualization, and visualization capabilities. This helps you prioritize critical security issues, respond at scale to reduce risks, improve team productivity, and better protect your cloud environment.

Here’s a quick look at the new AWS Security Hub.

With this new enhancement, AWS Security Hub integrates security capabilities like Amazon GuardDuty, Amazon Inspector, AWS Security Hub Cloud Security Posture Management (CSPM), Amazon Macie, and other AWS security capabilities to help you gain visibility across your cloud environment through centralized management in a unified cloud security solution. 

Getting started with the new AWS Security Hub
Let me walk you through how to get started with AWS Security Hub.

If you’re a new customer to AWS Security Hub, you need to navigate to the AWS Security Hub console to enable AWS security capabilities and capabilities and start assessing risk across your organization. You can learn more on the Documentation page.

After you have AWS Security Hub enabled, it will automatically consume data from supporting security capabilities you’ve enabled, such as Amazon GuardDuty, Amazon Inspector, Amazon Macie, and AWS Security Hub CSPM. You can navigate to the AWS Security Hub console to view these findings and benefit from insights created through correlation of findings across these capabilities.

As security risks are uncovered, they’re presented in a redesigned Security Hub summary dashboard. The new Security Hub summary dashboard provides a comprehensive, unified view of your AWS security posture. The dashboard organizes security findings into distinct categories, making it easier to identify and prioritize risks.

The new Exposure summary widget helps you identify and prioritize security exposures by analyzing resource relationships and signals from Amazon Inspector, AWS Security Hub CSPM, and Amazon Macie. These exposure findings are automatically generated and are a key part of the new solution, highlighting where your critical security exposures are located. You can learn more about exposure on the Documentation page.

AWS Security Hub now provides a Security coverage widget designed to help you identify potential coverage gaps. You can use this widget to identify where you’re missing coverage by the security capabilities that power Security Hub. This visibility helps you identify which capabilities, accounts, and features you need to address to improve your security coverage.

As you can see on the navigation menu, AWS Security Hub is organized into five key areas to streamline security management:

  • Exposure: Provides visibility into all exposure findings, a security vulnerability or misconfiguration that could potentially expose an AWS resource or system to unauthorized access or compromise, generated by Security Hub, helping you identify resources that might be accessible from outside your environment
  • Threats: Consolidates all threat findings generated by Amazon GuardDuty, showing potential malicious activities and intrusion attempts
  • Vulnerabilities: Displays all vulnerabilities detected by Amazon Inspector, highlighting software flaws and configuration issues
  • Posture management: Shows all posture management findings from AWS Security Hub Cloud Security Posture Management (CSPM), helping provide compliance with security best practices
  • Sensitive data: Presents all sensitive data findings identified by Amazon Macie, helping you track and protect your sensitive information

When you navigate to the Exposure page, you’ll see findings grouped by title, with severity levels clearly indicated to help you focus on critical issues first.

To explore specific exposures, you can select any finding to see affected resources. The panel includes key information about the implicated resource, account, Region, and when the issue was detected.

In this panel, you’ll also find an attack path visualization that is particularly useful for understanding complex security relationships. For network exposure paths, you can see all components involved in the path—including virtual private clouds (VPCs), subnets, security groups, network access control lists (ACLs), and load balancers—helping you identify exactly where to implement security controls. The visualization also highlights Identity and Access Management (IAM) relationships, showing how permission configurations might allow privilege escalation or data access. Resources with multiple contributing traits are clearly marked so you can quickly identify which components represent the greatest risk.

The Threats dashboard provides actionable insights into potential malicious activities detected by Amazon GuardDuty, organizing findings by severity so you can quickly identify critical issues like unusual API calls, suspicious network traffic, or potential credential compromises. The dashboard includes GuardDuty Extended Threat Detection findings, with all “Critical” severity threats representing these Extended Threat Detections that require immediate attention.

Similarly, the Vulnerabilities dashboard from Amazon Inspector provides a comprehensive view of software vulnerabilities and network exposure risks. The dashboard highlights vulnerabilities with known exploits, packages requiring urgent updates, and resources with the highest numbers of vulnerabilities.

Another valuable new feature is the Resources view, which provides an inventory of all resources deployed in your organization covered by AWS Security Hub. You can use this view to quickly identify which resources have findings against them and filter by resource type or finding severity. Selecting any resource provides detailed configuration information without needing to pivot to other consoles, streamlining your investigation workflow.

The new Security Hub also offers integration capabilities to help you comprehensively monitor your cloud environments and connect with third-party security solutions. This gives you the flexibility to create a unified security solution tailored to your organization’s specific needs.

For example, with integration capability, when viewing a security finding, you can select the Create ticket option and choose your preferred ticketing integration.

Additional things to know
Here are a couple of things to note:

  • Availability – During this preview period, the new AWS Security Hub is available in following AWS Regions: US East (N. Virginia, Ohio), US West (N. California, Oregon), Africa (Cape Town), Asia Pacific (Hong Kong, Jakarta, Mumbai, Osaka, Seoul, Singapore, Sydney, Tokyo), Canada (Central), Europe (Frankfurt, Ireland, London, Milan, Paris, Stockholm), Middle East (Bahrain), and South America (São Paulo).
  • Pricing – The new AWS Security Hub is available at no additional charge during the preview period. However, you will still incur costs for the integrated capabilities including Amazon GuardDuty, Amazon Inspector, Amazon Macie, and AWS Security Hub CSPM.
  • Integration with existing AWS security capabilities – Security Hub integrates with Amazon GuardDuty, Amazon Inspector, AWS Security Hub CSPM, and Amazon Macie, providing a comprehensive security posture without additional operational overhead.
  • Enhanced data interoperability – The new Security Hub uses the Open Cybersecurity Schema Framework (OCSF), enabling seamless data exchange across your security capabilities with normalized data formats.

To learn more about the enhanced AWS Security Hub and join the preview, visit the AWS Security Hub product page.

Happy building!

— Donnie

AWS Backup adds new Multi-party approval for logically air-gapped vaults

Post Syndicated from Veliswa Boya original https://aws.amazon.com/blogs/aws/aws-backup-adds-new-multi-party-approval-for-logically-air-gapped-vaults/

Today, we’re announcing the general availability of a new capability that integrates AWS Backup logically air-gapped vaults with Multi-party approval to provide access to your backups even when your AWS account is inaccessible due to inadvertent or malicious events. AWS Backup is a fully managed service that centralizes and automates data protection across AWS services and hybrid workloads. It provides core data protection features, ransomware recovery capabilities, and compliance insights and analytics for data protection policies and operations.

As a backup administrator, you use AWS Backup logically air-gapped vaults to securely share backups across accounts and organizations, logically isolate your backup storage, and support direct restore to help reduce recovery time following an inadvertent or malicious event. However, if a bad or unintended actor gains root access to your backup account or the management account of your organization, your backups suddenly become inaccessible, even though they’re still safely stored in the logically air-gapped vault. While traditional account recovery involved working through support channels, AWS Backup with Multi-party approval delivers immediate access to recovery tools, empowering you with faster resolution times and greater control over your recovery timeline.

Multi-party approval for AWS Backup logically air-gapped vaults adds an additional layer of protection for you to recover your application data even when your AWS account becomes completely inaccessible. Using Multi-party approval, you can create approval teams which consist of highly trusted individuals in your organization, then associate them with your logically air-gapped vault. If you get locked out of your AWS accounts due to inadvertent or malicious actions, you can request your own approval team to authorize sharing of your vault from any account, even those outside your AWS Organizations account. Once approved, you gain authorized access to your backups and can begin your recovery process.

How it works
Multi-party approval for AWS Backup logically air-gapped vaults combines the security of logically air-gapped vaults with the governance of Multi-party approval to create a recovery mechanism that works even when your AWS account is compromised. Here’s how it works:

1. Approval team creation
First, you create an approval team in your AWS Organizations management account. If the management account is new, first create an AWS Identity and Access Management (IAM) Identity Center instance before creating the approval team. The approval team consists of trusted individuals (IAM Identity Center users) who will be authorized to approve vault sharing requests. Each approver receives an invitation to join the approval team through a new Approval portal.

2. Vault association
When your approval team is active, you share it with accounts that own logically air-gapped vaults using AWS Resource Access Manager (AWS RAM) to safeguard against requests for approval from arbitrary accounts. Backup administrators can then associate this approval team with new or existing logically air-gapped vaults.

3. Protection against compromise
If your AWS account becomes compromised or inaccessible, you can request access to your backups from a different account (a clean recovery account). This request includes the Amazon Resource Name (ARN) of the logically air-gapped vault in the format arn:aws:backup:<region>:<account>:backup-vault:<name> and an optional vault name and comment.

4. Multi-party approval
The request is sent to the approval team, who review it through the approval portal. When the minimum required number of approvers authorize the request, the vault is automatically shared with the requesting account. All requests and approvals are comprehensively logged in AWS CloudTrail.

5. Recovery process
With access granted, you can immediately start restoring or copying your data in the new recovery account without waiting for your compromised account to be remediated.

This approach provides an entirely separate authentication path to access and recover your backups, completely independent of your AWS account credentials. Even if the bad actor has root access to your account, they can’t prevent the approval team-based recovery process.

1. Create a new logically air-gapped vault
To create a new logically air-gapped vault, provide a name, tags (optional), and vault lock properties.

2. Assign an approval team
When the vault has been created, choose Assign approval team to assign it with an existing approval team.

Choose an existing approval team from the drop-down menu then select Submit to finalize the assignment.

Now your approval team is assigned to your logically air-gapped vault.

Good to know
It’s essential to test your recovery process before an actual emergency:

  1. From a different AWS account, use the AWS Backup console or API to request sharing of your logically air-gapped vault by providing the vault ID and ARN.
  2. Request approval of your request from the approval team.
  3. Once approved, verify that you can access and restore backups from the vault in your testing account.

As a best practice, monitor the health of your approval team regularly using AWS Backup Audit Manager to ensure they have sufficient active participants to meet your approval threshold.

Multi-party approval for enhanced cloud governance
Today, we’re also announcing the general availability of a new capability that AWS account administrators can use to add Multi-party approval to their product offerings. As highlighted in this post, AWS Backup is the first service to integrate this capability. With Multi-party approval, administrators can enable application owners to guard sensitive service operations with a distributed review process.

Good to know
Multi-party approval provides several significant security advantages:

  • Distributed decision-making, eliminating single points of failure
  • Full auditability through AWS CloudTrail integration
  • Protection against compromised credentials
  • Formal governance for compliance-sensitive operations
  • Consistent approval experience across integrated services

Now available

Multi-party approval is available today in all AWS Regions where AWS Organizations is available. Multi-party approval for AWS Backup logically air-gapped vaults is available in all AWS Regions where AWS Backup is available.

– Veliswa.

New AWS Shield feature discovers network security issues before they can be exploited (Preview)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/new-aws-shield-feature-discovers-network-security-issues-before-they-can-be-exploited-preview/

Today, I’m happy to announce AWS Shield network security director (preview), a capability that simplifies identification of configuration issues related to threats such as SQL injections and distributed denial of service (DDoS) events, and proposes remediations. This feature identifies and analyzes network resources, connections, and configurations. It compares them against AWS best practices to create a network topology that highlights resources requiring protection.

Organizations today face significant challenges in maintaining a robust network security posture. Security teams often struggle to efficiently discover all resources in their environments, understand how these resources are interconnected, and identify which security services are currently configured. Additionally, they find determining how well resources are configured relative to AWS best practices requires considerable expertise and effort. Many teams find it difficult to identify which network security services and rule sets would best protect their applications from common and emerging threats.

AWS Shield network security director addresses these challenges through three key capabilities. First, it performs comprehensive analysis to discover resources across your AWS accounts, identify connectivity between resources, and determine which network security services and configurations are currently in place. Second, it prioritizes resources by severity level based on AWS network security best practices and threat intelligence. Finally, it provides specific remediation recommendations such as step-by-step instructions for implementing the right AWS security services, including AWS WAF, Amazon Virtual Private Cloud (Amazon VPC) security groups, and Amazon VPC network access control lists (ACLs) to protect your resources.

The service supports critical network security use cases, including protecting applications against internet-born threats and controlling human access to resources based on port, protocol, or IP address range. It provides network analysis to discover assets and delivers analysis that eliminates time-consuming manual processes for identifying resources that need protection. The service offers resource prioritization by assigning security findings a severity level based on network context and adherence to AWS best practices, helping you focus on what matters most. Additionally, it supplies actionable recommendations with specific guidance on which services and configurations will address each security gap. You can also get answers, in natural language, from AWS Shield network security director from within Amazon Q Developer in the AWS Management Console and chat applications.

Getting started with AWS Shield network security director
To use AWS Shield network security director, I need to initiate a network analysis of my AWS resources. I go to the AWS WAF & Shield console and choose Getting started under AWS Shield network security director in the navigation pane. I choose Get started, which takes me to the configuration page. On this page, I can choose how to perform my first network analysis: I can assess findings from across all supported Regions or from my current Region only. I select Start network analysis.

After the analysis is completed, the dashboard page shows a breakdown of resource types by severity level and the most common categories of network security findings associated with their resources. Resources are categorized by type and severity level (critical, high, medium, low, informational), making it easy to identify which areas need immediate attention.

Next, I explore the Resources section to understand the distribution of my assets and filter by severity level in my environment. I can use Resource overview to review a specific severity level, which will redirect me to the Resources under Network security director with the associated severity level filter. I choose the resources that have Medium severity level.

I choose a specific resource to view its network topology map showing how it connects to other resources and associated findings. This visualization helps me understand the potential impact of security configurations and identify exposed paths. I review detailed findings such as “Allows unrestricted inbound access (0.0.0.0/0) on all ports” with severity ratings.

Next, I go to Findings under Network security director, which shows common configuration issues. For each finding, I receive detailed information and recommended remediation steps. The service rates the severity of findings (high, medium, low) to help me prioritize my response. Critical-severity findings such as “CloudFront origin is also internet accessible without CloudFront protections” or high-severity findings such as “Allows unrestricted inbound access (0.0.0.0/0) on all ports” are presented first, followed by medium- and low-severity issues.

You can analyze your network security configurations, in natural language, with AWS Shield network security director within Amazon Q Developer in the AWS Management Console and chat applications. For example, you can say “Do I have any network security issues on my CloudFront distributions?” or “Are any of my resources vulnerable to bots and scrapers?” This integration helps security teams quickly understand their security posture and receive guidance on implementing best practices without having to navigate through extensive documentation.

To explore this capability, I ask “What are my most critical network security issues?” in the Explore with Amazon Q section. Amazon Q analyzes my network security configuration and generates a response based on the security assessment of my AWS environment.

With this comprehensive view of your network security, you can now make data-driven decisions to strengthen your defenses against emerging threats.

Join the preview
AWS Shield network security director is available in the US East (N. Virginia) and Europe (Stockholm) Regions. The Amazon Q Developer capability to analyze network security configurations is available in preview in US East (N. Virginia). To begin strengthening your network security, visit the AWS Shield network security director console and initiate your first network security analysis.

For more information, visit the AWS Shield product page.

— Esra

Amazon CloudFront simplifies web application delivery and security with new user-friendly interface

Post Syndicated from Micah Walter original https://aws.amazon.com/blogs/aws/amazon-cloudfront-simplifies-web-application-delivery-and-security-with-new-user-friendly-interface/

Today, we’re announcing a new simplified onboarding experience for Amazon CloudFront that developers can use to accelerate and secure their web applications in seconds. This new experience, along with improvements to the AWS WAF console experience, makes it easier than ever for developers to configure content delivery and security services without requiring deep technical expertise.

Setting up content delivery and security for web applications traditionally required navigating multiple Amazon Web Services (AWS) services and making numerous configuration decisions. With this new CloudFront onboarding experience, developers can now create a fully configured distribution with DNS and a TLS certificate in just a few clicks.

Amazon CloudFront offers compelling benefits for organizations of all sizes looking to deliver content and applications globally. As a content delivery network (CDN), CloudFront significantly improves application performance by serving content from edge locations closest to your users, reducing latency and improving user experience. Beyond performance, CloudFront provides built-in security features that protect your applications from distributed denial of service (DDoS) attacks and other threats at the edge, preventing malicious traffic from reaching your origin infrastructure. The service automatically scales with your traffic demands without requiring any manual intervention, handling both planned and unexpected traffic spikes with ease. Whether you’re running a small website or a large-scale application, the CloudFront integration with other AWS services and the new simplified console experience makes it easier than ever to implement these essential capabilities for your web applications.

Streamlined CloudFront configuration

The new CloudFront console experience guides developers through a simplified workflow that starts with the domain name they want to use for their distribution. When using Amazon Route 53, the experience automatically handles TLS certificate provisioning and DNS record configuration, while incorporating security best practices by default. This unified approach eliminates the need to switch between multiple services like AWS Certificate Manager, Route 53, and AWS WAF, and offers developers a faster time to production without the need to dive deep on the nuanced configuration options of each service.

For example, a developer can now create a secure CloudFront distribution for their applications fronted by a load balancer by entering their domain name and selecting their load balancer as the origin. The console automatically recommends optimal CDN and security configurations based on the application type and requirements, and developers can deploy with confidence knowing they’re following AWS best practices.

For developers who wish to host a static website on Amazon Simple Storage Service (Amazon S3), CloudFront provides several important benefits. First, it improves your website’s performance by caching content at edge locations closer to your users, reducing latency and improving page load times. Second, it helps protect your S3 bucket by acting as a security layer—CloudFront can be configured to be the only way to access your content, preventing direct access to your S3 bucket. The new experience automatically configures these security best practices for you.

Enhanced security integration with AWS WAF

Complementing the new CloudFront experience, we’re also introducing an improved AWS WAF console that features intelligent Rule Packs—curated sets of security rules based on application type and security requirements. These Rule Packs enable developers to implement comprehensive security controls without needing to be security experts.

When creating a CloudFront distribution, developers can now enable AWS WAF protection through an integrated experience that uses these new Rule Packs. The console provides clear recommendations for security configurations that developers can use to preview and validate their settings before deployment.

Web applications face numerous security threats today, including SQL injection attacks, cross-site scripting (XSS), and other OWASP Top 10 vulnerabilities. With the new AWS WAF integration, you automatically get protection against these common attack vectors. The recommended Rule Packs provide immediate protection against malicious bot traffic, common web exploits, and known bad actors while preventing direct-to-origin attacks that could overwhelm your infrastructure.

Let’s take a look

If you’ve ever created an Amazon CloudFront distribution, you’ll immediately notice that things have changed. The new experience is straightforward to follow and understand. For my example, I chose to create a distribution for a static website using Amazon S3 as my origin.

New onboarding experience for Amazon CloudFront

In Step 1, I give my distribution a name and select from Single website or app or the new Multi-tenant architecture option, which I can use to configure distributions that use multiple domains but share a common configuration. I choose Single website or app and enter an optional domain name. With the new experience, I can use the Check domain button to verify I have my domain as a Route 53 zone file.

Next, I select the origin for the distribution, which is where CloudFront will fetch the content to serve and cache. For my Origin type, I select Amazon S3. As the preceding screenshot shows, there are several additional options to choose from. Each of the options is designed to make configuration as straightforward as possible for the most popular use cases. Next, I select my S3 bucket, either by typing in the bucket name or using the Browse S3 button.

Next, I have several settings related to using Amazon S3 as my origin. The Grant CloudFront access to origin option is an important one. This option (selected by default) will update my S3 bucket policy to allow CloudFront to access my bucket and will configure my bucket for origin access control. This way, I can use a completely private bucket and know that assets in my bucket can only be accessed through CloudFront. This is a critical step to keeping my bucket and assets secure.

In the next step, I’m presented with the option to configure AWS WAF. With AWS WAF enabled, my web servers are better protected because it inspects each incoming request for potential threats before allowing them to make their way to my web servers. There is a cost to enabling AWS WAF, and as you can see in the following screenshot, there is a calculator to help estimate additional charges.

New onboarding experience for Amazon CloudFront

Now available

The new CloudFront onboarding experience and enhanced AWS WAF console are available today in all AWS Regions where these services are offered. You can start using these new features through the AWS Management Console. There are no additional charges for using these new experiences—you pay only for the CloudFront and AWS WAF resources you use, based on their respective pricing models.

To learn more about the new CloudFront onboarding experience and AWS WAF improvements, visit the Amazon CloudFront Documentation and AWS WAF Documentation. Start building faster, more secure web applications today with these simplified experiences.