Tag Archives: Security Blog

Enforce zero data retention on Amazon Bedrock with Bedrock Projects and service control policies

Post Syndicated from Rob Higareda original https://aws.amazon.com/blogs/security/enforce-zero-data-retention-on-amazon-bedrock-with-bedrock-projects-and-service-control-policies/

With the introduction of models that require data sharing with third-party providers—such as Claude Fable 5—organizations need a way to centrally enforce data retention policies. Amazon Bedrock gives you control over whether your prompts and model outputs are retained after an inference request completes. You might need a way to enforce your retention settings across all accounts and have granular control of project data retention when compatible with the selected model.

In this blog post, I walk you through how Amazon Bedrock data retention modes work, the tools available for managing retention—including Amazon Bedrock Projects and service control policies (SCPs)—and how to verify your policy settings are working correctly.

In this post, you will learn:

  • How Amazon Bedrock data retention modes work and what each mode means for your data
  • How to use Amazon Bedrock Projects with compatible models to isolate workloads with different retention needs
  • How to write and deploy an SCP that prevents anyone in your organization from enabling data sharing
  • How data retention modes interact with cross-Region inference profiles
  • How to verify your configuration is working correctly

Understanding data retention modes

You can use Amazon Bedrock to control data retention through a mode setting on your account. This determines what happens to your prompts and outputs after each inference request, which is important to understand as you assess your compliance needs. Not all models require data retention or data sharing, and you might continue to use Amazon Bedrock with models that don’t require data retention or data sharing. See the Amazon Bedrock documentation for the current list of models that require data retention or data sharing. Ultimately, it’s your responsibility as the customer to select models that align with your compliance needs.

The following modes govern how Amazon Bedrock handles your data:

Mode Behavior Data shared with provider
none Zero data retention. Prompts and responses are processed and immediately discarded. No
default No data is shared with model providers. Some models might require data retention for trust and safety checks for up to 30 days. Consult the model’s terms for specifics. This mode also allows APIs that inherently require retention (for example, Batch API, Responses API with store=true). Models that support zero retention will still operate with zero retention. No
inherit No explicit setting applied, defers to the next higher scope (project defers to account defers to service default). This is the default for new accounts. No
provider_data_share Data is shared with the model provider and retained for up to 30 days for trust and safety. Yes

Understanding mode as a ceiling, not a floor

The most important concept to understand: your configured mode is the upper limit of retention you’re willing to accept; it is not what every request will use. Setting your account to provider_data_share doesn’t mean all your requests suddenly start retaining and sharing data. Models that support zero data retention will still operate with zero retention regardless of your account-level setting.

Think of it as a permissions ceiling:

Your account mode Model you invoke What happens
provider_data_share Claude Sonnet (supports none) Zero retention, Sonnet doesn’t require data sharing or data retention
provider_data_share Claude Fable 5 (requires provider_data_share) Data retained for up to 30 days and might be shared with provider, Fable 5 requires data sharing and data retention
none Claude Sonnet (supports none) Zero retention, no data sharing
none Claude Fable 5 (requires provider_data_share) Blocked, your ceiling is below what the model requires, calls to this model will be denied
default Claude Sonnet (supports none) Zero retention, Sonnet supports it, no data retention or data sharing
default A model requiring retention for safety checks Data is retained, model requires it and your ceiling allows it

Key takeaway: Your mode setting declares the maximum level of data retention you will accept. Models that support zero retention will continue to operate that way regardless of your account setting. Amazon Bedrock is designed so that you do not get more retention than necessary just because your account mode allows it.

Important: provider_data_share isn’t inherited from a model—it’s an explicit opt-in at the account or project level. If your account is set to inherit or default, no model will trigger provider data sharing unless you configure it within your account or project.

Note on inherit behavior: The inherit mode defers to the next scope up in the hierarchy (project defers to account defers to service default). If a project is set to inherit and the account above it is set to provider_data_share, the project will inherit provider_data_share. You will not inherit provider_data_share from a model—that requires an explicit setting at the account or project level.

Note on APIs that require retention: Some Amazon Bedrock APIs require data retention to function regardless of model support, for example, the Batch API and the Responses API with store=true. Setting your mode to none will block these APIs. This is expected behavior: your ceiling of none means you require no retention, so APIs that can’t operate without retention are unavailable.

Why does provider_data_share exist?

Some foundation models require the provider_data_share mode to function. As AI models evolve, so must the mechanism to protect customers and the safety of their use. Models that require provider_data_share have allowed_modes: ["provider_data_share"], meaning they will appear as unavailable unless the account has explicitly opted in. This is by design: AWS requires you to make a conscious decision to share data before you as a customer can use these models. See the current list of models available through Amazon Bedrock and their retention requirements, which can change as new models are released.

If your regulatory requirements, internal policies, or customer commitments prohibit data sharing with third-party model providers, you can enforce this at multiple levels. Amazon Bedrock provides several tools for managing data retention, from fine-grained project-level settings to organization-wide enforcement.

Tools for managing data retention

Amazon Bedrock gives you multiple layers of control over data retention. You can use them independently or combine them for defense-in-depth:

Tool Scope Use case
Amazon Bedrock console Per-account, per-AWS Region Quick configuration and visibility; view and change your retention mode directly in the AWS Management Console.
Amazon Bedrock Projects Per-project within an account Isolate workloads with different retention needs within the same account for compatible models
SCPs Organization-wide Use to prevent any account from opting in to data sharing
IAM policies Per-account or per-principal Fine-grained control, including the management account (which SCPs don’t cover)

Using Amazon Bedrock Projects for granular control

Not every workload in an account has the same data retention requirements. If you’re using the bedrock-mantle endpoint (OpenAI-compatible APIs), you can use Amazon Bedrock Projects to isolate traffic that can accept data retention from traffic that must not be retained—even within the same account.

For example, you might have:

  • A research project where your team needs access to the latest models (including those requiring provider_data_share) for experimentation
  • A production project handling customer data where zero retention is mandatory

With Amazon Bedrock Projects, you can set provider_data_share on the research project while keeping the production project locked to none. Each project enforces its own retention ceiling independently.

How project-level retention works:

  • Each project can have its own data retention mode setting.
  • A project set to inherit will inherit its mode from the account level.
  • A project set to none enforces zero retention regardless of the account setting. Traffic routed through that project can’t trigger data sharing.
  • A project set to provider_data_share allows models requiring data sharing, but only for requests within that project.

This gives organizations the flexibility to adopt new models incrementally while maintaining strict data governance on sensitive workloads. You can manage project settings using the Amazon Bedrock console or the bedrock-mantle API.

Important: Amazon Bedrock Projects are only available on the bedrock-mantle endpoint. They work with models accessed using the OpenAI-compatible APIs (Responses, Chat Completions) and the Anthropic Messages API on the mantle endpoint. Not all models are available on bedrock-mantle; check the endpoint availability by models page for current support.

Workload isolation on the bedrock-runtime endpoint

If you’re using the bedrock-runtime endpoint (Invoke, Converse APIs), project-level data retention isn’t available. The account-level retention mode applies to all requests made through bedrock-runtime.

To achieve workload-level isolation on bedrock-runtime, use separate AWS accounts:

  • Place workloads that need provider_data_share in one account (or OU) without the SCP
  • Place workloads that require zero retention in a separate account (or OU) with the SCP applied

You can use AWS Organizations OUs to group accounts by retention policy and apply SCPs selectively:

Organization Root
├── OU: Zero-Retention (SCP attached — blocks provider_data_share)
│   ├── Account: Production-App-A
│   └── Account: Production-App-B
└── OU: Research (no SCP — allows provider_data_share)
    └── Account: ML-Experimentation

Combining projects with SCPs: If you use an SCP to enforce none at the organization level, it overrides all project-level settings on bedrock-mantle. For accounts where you want project-level flexibility, don’t apply the SCP—use project-level isolation instead. For accounts that must never have data sharing under any circumstances, the SCP provides an unbypassable guarantee across both endpoints.

Using SCPs for organization-wide enforcement

For organizations that need an absolute guarantee that no account can enable data sharing—regardless of who has admin access or which endpoint they use—SCPs provide the strongest enforcement mechanism. SCPs apply to both the Amazon Bedrock control plane (bedrock:PutAccountDataRetention) and the mantle endpoint (bedrock-mantle:PutAccountDataRetention, bedrock-mantle:CreateProject, bedrock-mantle:UpdateProject).

Enforcing zero data retention with an SCP

In this section, I cover how you can use SCPs to manage your data retention policy. I introduce what an SCP is and provide some policies that you can use in your organization.

What is an SCP?

A service control policy (SCP) is a guardrail set at the organization level. It overrides every principal in the organization, including account administrators and root users. Even if someone has full admin permissions, an SCP deny can’t be overridden by an AWS Identity and Access Management (IAM) policy.

SCPs are managed in AWS Organizations and can be attached at different levels:

  • Root – Applies to every account in the organization
  • Organizational unit (OU) – Applies to all accounts in that OU
  • Individual account – Applies only to that specific account

Important: The SCP must be attached to the root OU to cover all accounts. If attached to a child OU, accounts outside that OU will not be protected. Organization admin accounts don’t inherit SCP controls.

The SCP policy

The following policy prevents anyone in the organization from changing the Amazon Bedrock data retention mode to anything other than none.

Important: New accounts default to inherit (not none). Before attaching this SCP, you must explicitly set each account to none. Start by running the following in each account:

aws bedrock put-account-data-retention --region us-east-1 --mode none

If you have hundreds, or thousands of AWS accounts, you will need a way to scale this. See the AWS re:Post article Automate Bedrock Zero Data Retention Across All Accounts in Your Organization to learn how.

Amazon Bedrock policy:

This policy is used to restrict data retention to only be set to none. Any other value than none will be denied.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "RESTRICTBEDROCKDATARETENTION",
            "Effect": "Deny",
            "Action": [
                "bedrock:PutAccountDataRetention"
            ],
            "Resource": "*",
            "Condition": {
                "StringNotEquals": {
                    "bedrock:DataRetentionMode": "none"
                }
            }
        }
    ]
}

How it works

The Condition block uses StringNotEquals, meaning the deny fires for any value that isn’t none. This ensures:

Action Result
Setting mode to none Allowed
Setting mode to provider_data_share Denied by SCP
Setting mode to default Denied by SCP
Setting mode to inherit Denied by SCP

With all the preceding in place you might be wondering what this means for your organization:

  • No one can enable data sharing with model providers – Even account administrators receive Access Denied
  • Models requiring provider_data_share become permanently unavailable – Models that require data sharing (such as Claude Fable 5 and Claude Mythos 5, among others) will not work across the organization
  • All other models continue to work normally – Models that support none mode are unaffected
  • The setting cannot be bypassed – no IAM policy can override an SCP deny

Optional: Block project-level overrides

The bedrock-mantle endpoint supports project-level data retention settings. Without additional SCP coverage, someone could create or update a project with provider_data_share, bypassing the account-level restriction. To prevent this, extend your SCP to include the bedrock-mantle project actions:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "RESTRICTBEDROCKDATARETENTION",
            "Effect": "Deny",
            "Action": [
                "bedrock:PutAccountDataRetention",
                "bedrock-mantle:PutAccountDataRetention",
                "bedrock-mantle:CreateProject",
                "bedrock-mantle:UpdateProject"
            ],
            "Resource": "*",
            "Condition": {
                "StringNotEquals": {
                    "bedrock:DataRetentionMode": "none"
                }
            }
        }
    ]
}

Why doesn’t bedrock-runtime need project-level blocking? Projects don’t exist on the bedrock-runtime endpoint. The only way to change retention for bedrock-runtime traffic is the account-level bedrock:PutAccountDataRetention action, which the base SCP already blocks. The extra CreateProject and UpdateProject actions are only needed because bedrock-mantle allows per-project retention overrides; the project level control iisn’t required on bedrock-runtime.

Data retention and cross-Region inference

When using cross-Region inference profiles, it’s important to understand how data retention mode is evaluated: the mode is evaluated in the source AWS Region of your request, the Region where you make the API call. You don’t need to set the retention mode in every destination Region.

However, there’s an important caveat: while the mode check happens in your source Region, the data itself might be retained in the destination Region where the inference is processed. This is relevant for organizations tracking where retained data resides geographically.

What this means in practice

The following describes how this work in practice with data retention and inference.

  • If your source Region (for example, us-east-1) is set to provider_data_share, requests using a cross-Region inference profile will be permitted, regardless of the retention setting in the destination Region
  • If your source Region is set to none, requests to models requiring provider_data_share will be blocked at the source, before the request is ever routed to a destination Region
  • SCPs continue to apply globally, a single SCP at the root OU blocks provider_data_share in every Region automatically

SCPs are global

While data retention settings are helpful for granular control of data retention settings itself, SCPs can be used to apply data retention settings globally across all Regions automatically. A single SCP attached to the root OU blocks provider_data_share in every Region without needing to configure anything per-region. This is one of the key advantages of using an SCP for enforcement rather than relying on manual configuration.

Verify your configuration

You can verify your data retention settings and SCP enforcement using the AWS Software Development Kit, AWS Command Line Interface (AWS CLI), or the Amazon Bedrock console.

Check your current retention mode

The following provides are options that you can use for checking your current retention mode.

Using the Amazon Bedrock console:

In the AWS Management Console, go to Amazon Bedrock and choose Settings, and then choose Data retention. Here, you can see the current account-level retention mode and change it directly.

Using the AWS CLI (requires CLI version 2.35+):

aws bedrock get-account-data-retention --region us-east-1

Expected response:

{
  "mode": "none",
  "updatedAt": "2026-07-01T01:58:34.684Z"
}

Using the bedrock-mantle API (using a Bedrock API key):

curl https://bedrock-mantle.us-east-1.api.aws/v1/data_retention \
	-H "x-api-key: $BEDROCK_API_KEY"

Expected response:

{
  "mode": "none",
  "updated_at": 1719792000
}

Check a model’s effective mode and allowed modes

You can also use the bedrock-mantle API to check what retention mode is in effect for a specific model, and which modes that model supports:

curl https://bedrock-mantle.us-east-1.api.aws/v1/models/anthropic.claude-fable-5 \ 
  -H "x-api-key: $BEDROCK_API_KEY

Response:

{
  "id": "anthropic.claude-fable-5",
  "status": "available",
  "data_retention": {
    "mode": "provider_data_share",
    "source": "account",
    "allowed_modes": ["provider_data_share"]
  }
}

If the model shows "status": "unavailable", the status_reason field will explain the retention mode conflict.

Verify the SCP is working

To confirm your SCP is actively blocking data retention changes, attempt to set the mode to provider_data_share:

Using AWS CLI:

aws bedrock put-account-data-retention \
  --region us-east-1 \
  --mode provider_data_share

Using bedrock-mantle API:

curl -X PUT https://bedrock-mantle.us-east-1.api.aws/v1/data_retention \
  -H "x-api-key: $BEDROCK_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{ "mode": "provider_data_share" }'

If the SCP is working, you’ll receive an Access Denied error:

An error occurred (AccessDeniedException) when calling the PutAccountDataRetention operation:
User: arn:aws:iam::123456789012:user/admin is not authorized to perform:
bedrock:PutAccountDataRetention with an explicit deny in a service control policy

If the SCP is not working, the request will succeed. If this happens, immediately revert:

aws bedrock put-account-data-retention \
  --region us-east-1 \
  --mode none

Then troubleshoot your SCP attachment:

  • Verify the SCP is attached to the root OU, not a child OU
  • Check the SCP policy syntax and condition keys
  • Remember: the AWS Organizations management account is exempt from SCPs—use an IAM policy to enforce policies on that account

Enable data retention for models that require it

For accounts where you want to use models requiring provider_data_share (accounts where the SCP isn’t applied), set the mode using AWS CLI, the API, or the console:

Using AWS CLI:

aws bedrock put-account-data-retention \
  --region us-east-1 \
  --mode provider_data_share

Using bedrock-mantle API:

curl -X PUT https://bedrock-mantle.us-east-1.api.aws/v1/data_retention \
  -H "x-api-key: $BEDROCK_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{ "mode": "provider_data_share" }'

You can also do this in the Bedrock console in Data retention , under Settings.

Reset data retention back to none

To revert to zero data retention:

Using AWS CLI:

aws bedrock put-account-data-retention \
  --region us-east-1 \
  --mode none

Using bedrock-mantle API:

curl -X PUT https://bedrock-mantle.us-east-1.api.aws/v1/data_retention \
  -H "x-api-key: $BEDROCK_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{ "mode": "none" }'

Manage project-level data retention

You can set data retention at the project level to allow different workloads within the same account to have different retention policies. Update a project’s data retention mode using the bedrock-mantle API:

# Set a project to provider_data_share
curl -X POST https://bedrock-mantle.us-east-1.api.aws/v1/organization/projects/proj_abc123 \
  -H "x-api-key: $BEDROCK_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{ "data_retention": { "mode": "provider_data_share" } }'

# Set a project to none (zero retention)
curl -X POST https://bedrock-mantle.us-east-1.api.aws/v1/organization/projects/proj_abc123 \
  -H "x-api-key: $BEDROCK_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{ "data_retention": { "mode": "none" } }'

# Check a project's current setting
curl -X POST https://bedrock-mantle.us-east-1.api.aws/v1/organization/projects/proj_abc123 \
  -H "x-api-key: $BEDROCK_API_KEY"

How project-level retention resolves: The effective mode for any request is determined by taking the first non-inherit value in the project, account, model default hierarchy. If your project is set to none, it enforces zero retention regardless of the account setting. If your project is set to inherit, it defers to the account-level setting.

Note: Project-level data retention is managed exclusively through the bedrock-mantle API. There is no AWS CLI command for project-level settings. The preceding AWS CLI commands only manage the account-level setting through the Amazon Bedrock control plane.

Conclusion

In this post, I showed you the various methods for managing data retention within Amazon Bedrock, including project-level data retention and organization wide control you can implement using SCPs. Choose the combination that matches your requirements and consult the Amazon Bedrock documentation to confirm each model’s mode requirements before deployment.

For more information about Amazon Bedrock data retention, see the data retention documentation. For SCPs, see service control policies in the AWS Organizations User Guide.

Additional resources

Try the examples in this post and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.
Rob Higareda

Rob Higareda

Rob is a Principal Solutions Architect in the AWS Security Risk and Compliance organization at AWS, focused on risk assessment for AI-powered services. Rob joined AWS with 20+ years of experience as a systems engineer. He works primarily with regulated customers at AWS and is focused on security and infrastructure design.

Enforce least-privilege authorization in multi-agent AI chains using Cedar

Post Syndicated from Dhananjay Karanjkar original https://aws.amazon.com/blogs/security/enforce-least-privilege-authorization-in-multi-agent-ai-chains-using-cedar/

If you’re building multi-agent AI systems, you need to prevent authorization scope from silently expanding as agents delegate tasks through multi-hop chains. Without proper controls, an agent can potentially act beyond what the originating user authorized, even when role-based access control (RBAC) policies are in place. The OWASP Top 10 for Agentic Applications classifies this risk as ASI03: Identity & Privilege Abuse.

This post shows you how to address the potential risk using a three-layer policy model built with Cedar, an open source authorization policy language, deployed on Amazon Web Services (AWS). The reference implementation uses OAuth 2.0 for authentication and Cedar for authorization. A trusted identity provider authenticates the originating user, then Cedar policies enforce authorization across three layers using verified token claims.

Reference implementation overview

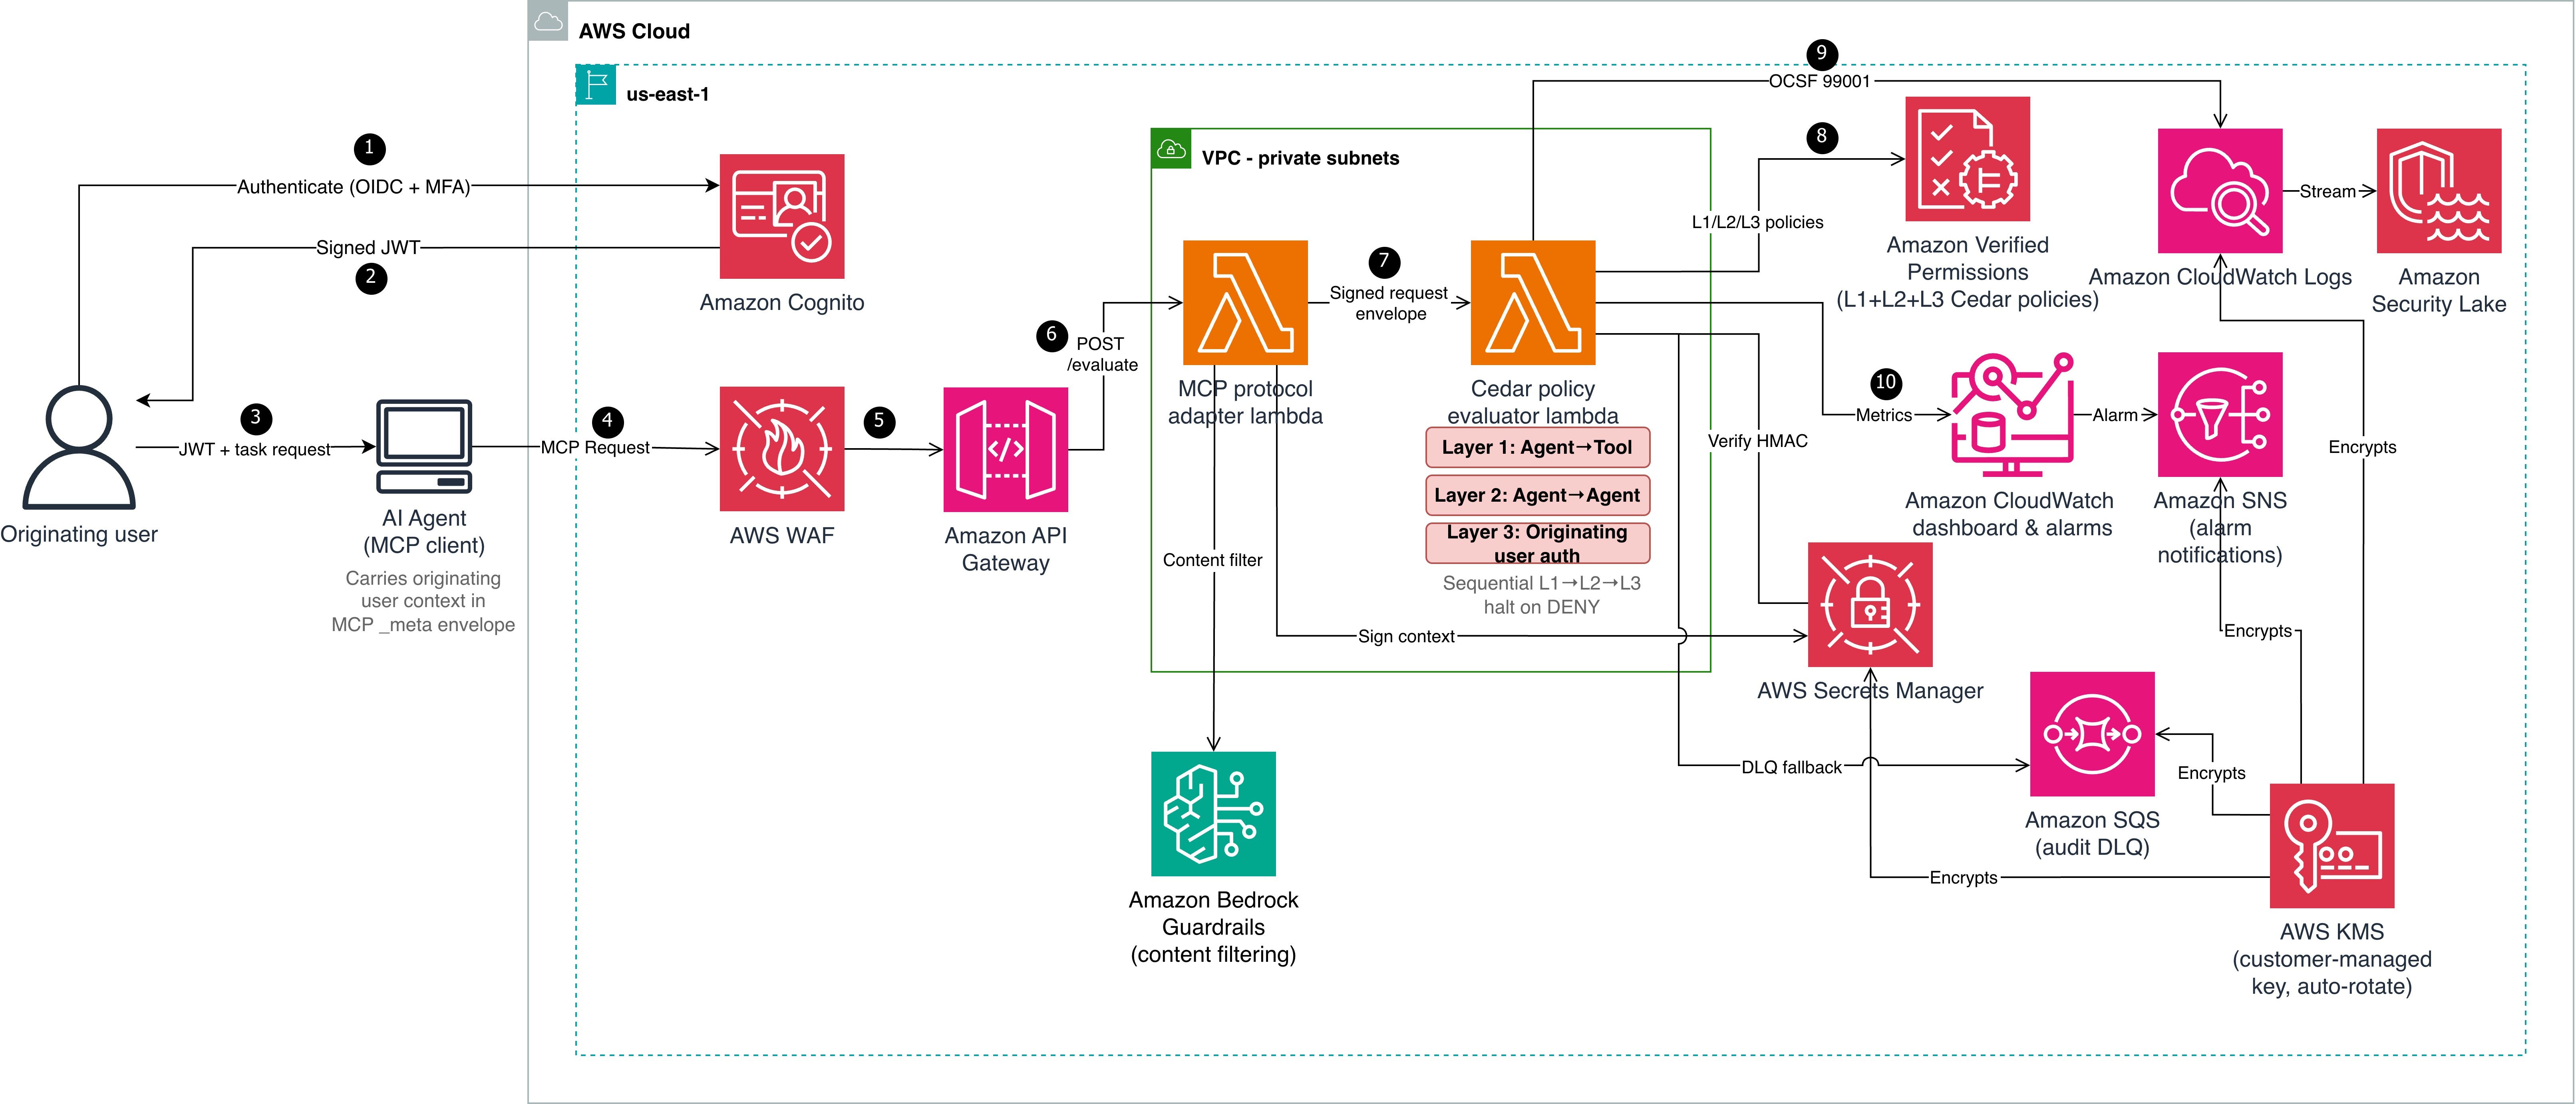
To enforce authorization at each hop in a multi-agent delegation chain, the reference implementation uses two AWS Lambda functions in sequence. A Model Context Protocol (MCP) adapter Lambda function normalizes inbound requests and cryptographically signs the originating user context. This prevents downstream tampering. A Cedar evaluator Lambda function evaluates three independent policy layers sequentially, halting on the first deny.

Table 1: Three-layer Cedar policy evaluation model

Layer What it checks Principal to resource
L1 – Agent-to-tool Whether the invoking agent has a sufficient trust score (1–5), belongs to the correct namespace (for example, payments), and is in the production lifecycle stage Agent to tool
L2 – Agent-to-agent delegation Whether the delegation hop count is within the hard limit of five, and whether requested tasks are a subset of the target agent’s registered capabilities Agent to agent
L3 – Originating user authorization Whether the human who initiated the chain has the required role (for example, admin), has completed MFA, and is within the allowed delegation depth Agent to tool (user in context)

Architecture

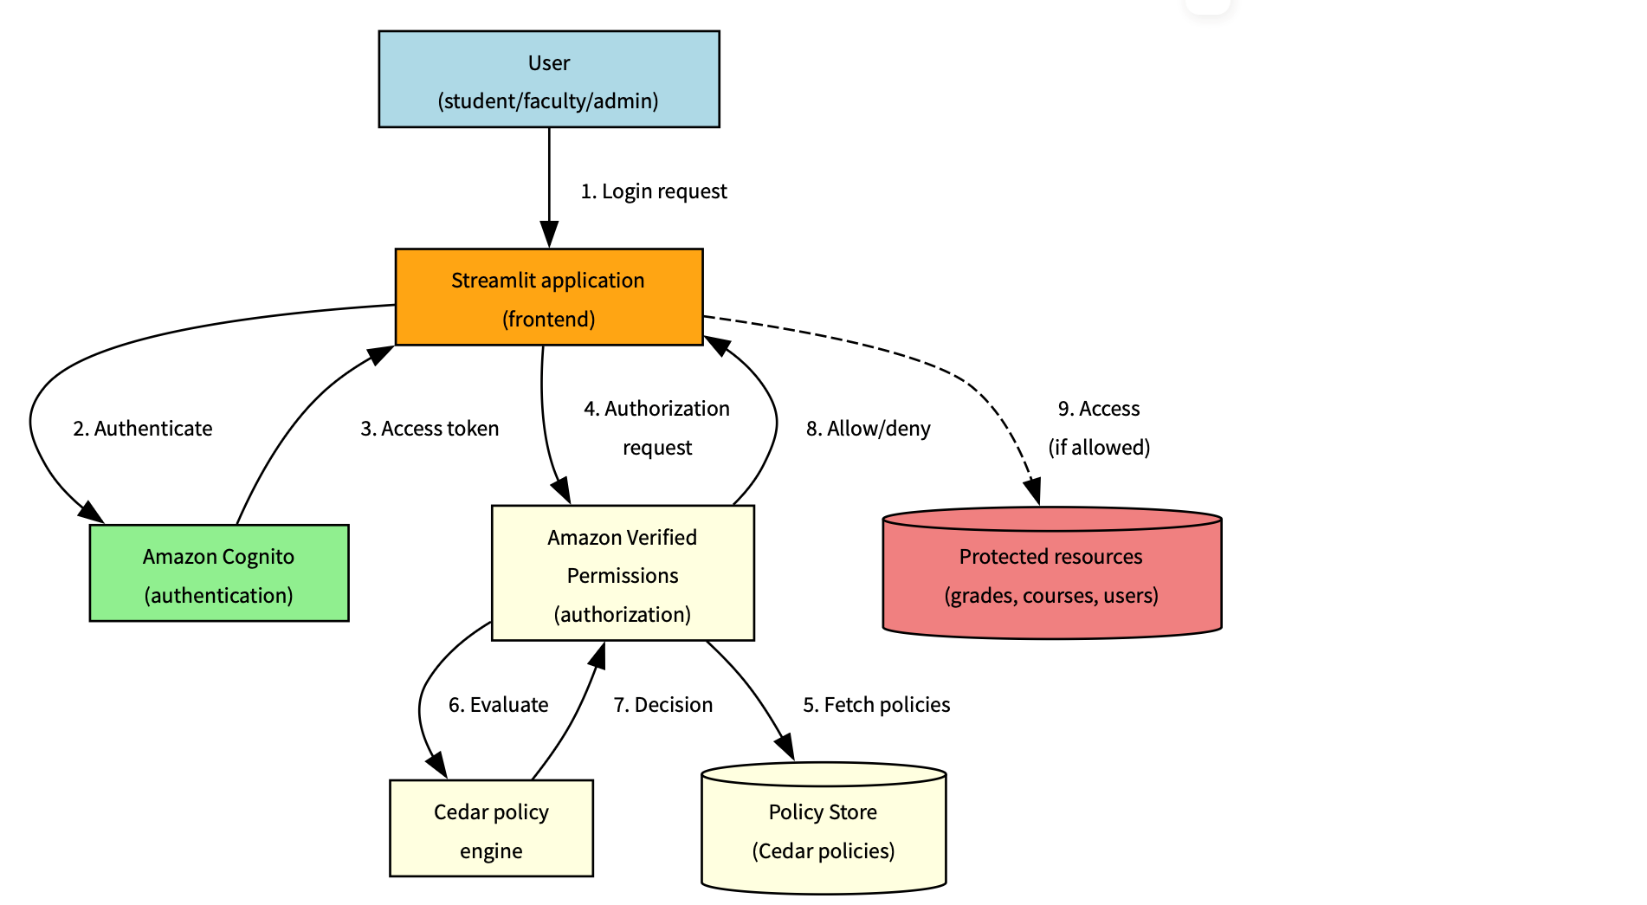
Cedar evaluates authorization but doesn’t establish identity. Before Cedar can evaluate context.originating_user.role or context.originating_user.mfa_verified, a trusted authentication layer must establish the user’s identity and produce verifiable claims. Steps 1–3 handle authentication; steps 4–10 handle authorization. The architecture shown in Figure 1 is described in the following lists:

Authentication (steps 1–3)

  1. The originating user authenticates with an OIDC-compliant identity provider (in this reference implementation, Amazon Cognito with TOTP multi-factor authentication (MFA)). The identity provider (IdP) issues a signed JSON Web Token (JWT) containing claims such as sub, role, amr (authentication methods), and session_id.
  2. Amazon Cognito returns the signed JWT to the user.
  3. The user passes the JWT and task request to the AI agent (MCP client). The agent carries the originating user context in the MCP _meta envelope.

Authorization pipeline (steps 4–10)

  1. The AI agent sends a Model Context Protocol (MCP) request to AWS WAF, which filters using CommonRuleSet, SQLiRuleSet, rate limiting, and body size constraints.
  2. Amazon API Gateway (with Amazon Cognito authorizer) verifies the JWT signature against the user pool’s public keys and rejects invalid or expired tokens. Valid requests are forwarded to the MCP protocol adapter Lambda function, which applies Amazon Bedrock Guardrails content filtering.
  3. The adapter extracts verified claims from the token and maps them to Cedar context attributes:
    1. JWT role claim : context.originating_user.role
    2. JWT amr includes MFA method: context.originating_user.mfa_verified = true
    3. JWT sub: context.originating_user.user_id
    4. JWT sid: context.originating_user.session_id
    5. JWT amr claim: context.originating_user.authentication_method

    The adapter then computes an HMAC-SHA256 signature over the user context (user_id, role, mfa_verified, authentication_method, and session_id in canonical order) using a key from AWS Secrets Manager.

  4. The adapter constructs a signed request envelope and invokes the Cedar evaluator Lambda function.
  5. The evaluator verifies the HMAC-SHA256 signature, retrieves L2 and L3 Cedar policies from Amazon Verified Permissions, and evaluates all three layers (L1, L2, and L3), halting on the first deny.
  6. The evaluator emits an Open Cybersecurity Schema Framework (OCSF) 99001 audit event to Amazon CloudWatch Logs. Failed emissions fall back to an Amazon Simple Queue Service (Amazon SQS) dead-letter queue (DLQ).
  7. Amazon CloudWatch dashboards and alarms monitor evaluation latency, deny rates, and DLQ depth. Alarm notifications route through Amazon Simple Notification Service (Amazon SNS).

Context integrity through delegation hops

Two mechanisms work together to protect identity across hops:

  • Hash-based Message Authentication Code (HMAC-SHA256) ensures integrity and authenticity. Every downstream evaluator verifies this signature before trusting the context.
  • OAuth 2.0 Token Exchange (RFC 8693) sets delegation scope using the on-behalf-of (OBO) pattern. When the orchestrator delegates to a downstream agent (data-bot), it exchanges the original token for a scoped OBO token that records who’s acting on behalf of whom and with what authority. The Cedar policies (detailed in Step 2: Three-layer policies) then check whether that scoped delegation is permitted and verify the originating user claims carried in the OBO token. Token exchange limits each downstream agent to only the delegated task’s scope instead of passing through the full original token. For enterprise deployments, use token exchange alongside HMAC. OAuth tracks who is acting on behalf of whom and with what scope. HMAC verifies that the context hasn’t been tampered with and came from a trusted source.

Prerequisites

The following prerequisites are needed to deploy the reference implementation. Before you begin, clone the repository:

git clone https://github.com/aws-samples/sample-cedar-agentic-ai-authorization.git
cd sample-cedar-agentic-ai-authorization

Verify that you have the following:

Walkthrough

In this walkthrough, you define the Cedar entity schema and policies, deploy the infrastructure with AWS CDK, and integrate your identity provider.

To define the Cedar entity schema

In this step, you define a schema with two entity types (Agent and Tool) and two actions (invoke_tool and delegate_task) in the AgentAuthz namespace. Notice that there is no User entity. Instead, you carry the originating user’s identity in the evaluation context record, which is a structured data object passed alongside each authorization request.

{
  "AgentAuthz": {
    "entityTypes": {
      "Agent": {
        "shape": {
          "type": "Record",
          "attributes": {
            "trust_level": { "type": "Long", "required": true },
            "namespace": { "type": "String", "required": true },
            "registered_capabilities": {
              "type": "Set", "element": { "type": "String" }, "required": true
            },
            "lifecycle_stage": { "type": "String", "required": true }
          }
        }
      },
      "Tool": {
        "shape": {
          "type": "Record",
          "attributes": {
            "namespace": { "type": "String", "required": true },
            "risk_level": { "type": "String", "required": true }
          }
        }
      }
    },
    "actions": {
      "invoke_tool": {
        "appliesTo": { "principalTypes": ["Agent"], "resourceTypes": ["Tool"] }
      },
      "delegate_task": {
        "appliesTo": { "principalTypes": ["Agent"], "resourceTypes": ["Agent"] }
      }
    }
  }
}

This schema is deployed to an Amazon Verified Permissions policy store by the VerifiedPermissionsStack CDK stack. In the reference implementation, the schema file is located at cedar-entity-schema.json.

Agent topology and attributes

The following tables show the agents and tools registered in this reference implementation, along with the attributes the Cedar evaluator function retrieves from the entity store. The test scenarios that follow trace requests through this topology.

Table 2: Agent attributes

Entity Type trust_level namespace lifecycle_stage registered_capabilities
orchestrator Agent 5 orchestration production

delegate_task

route_request

finance-agent Agent 3 payments production

process_payment

refund

data-bot Agent 4 data production

query_records

delete_records

Table 3: Tool attributes

Tool namespace risk_level
process_payment payments medium
delete_records data high
query_records data low

The orchestrator can delegate to both data-bot and finance-agent. Each agent can only invoke tools within its registered capabilities. The test scenarios below trace requests through these delegation paths.

To create three-layer Cedar policies

The following policies are deployed to the same Verified Permissions policy store. In the reference implementation, policy files are located under cedar/policies/ organized by layer: layer1-agent-to-tool/, layer2-agent-to-agent/, and layer3-originating-user-auth/.

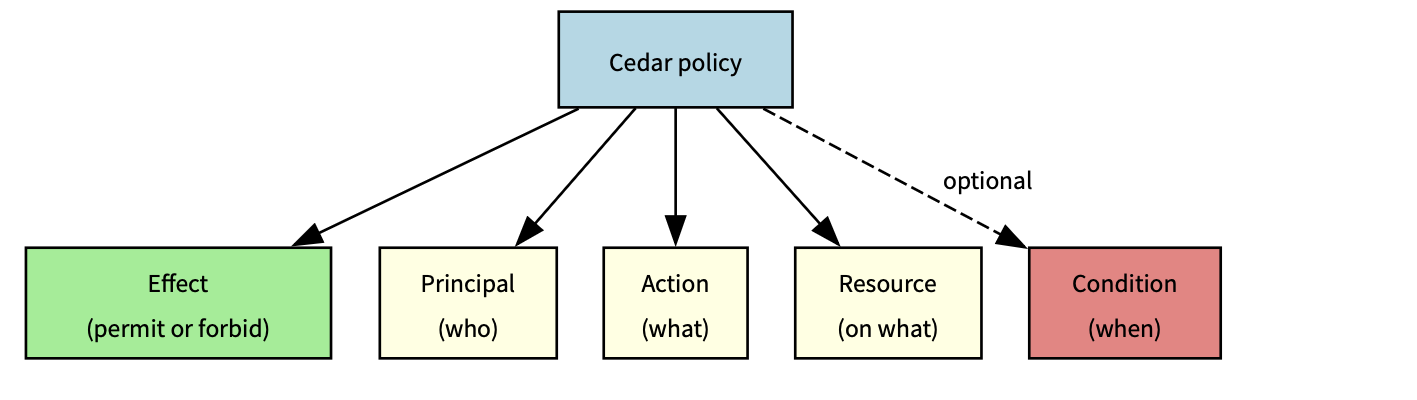
Layer 1 (agent-to-tool): This policy permits the finance-agent to invoke the process_payment tool only when three conditions are met: the agent’s trust score is at least 3, it belongs to the payments namespace, and it’s deployed in the production lifecycle stage. If any condition fails, the request is denied. The agent’s trust_level, namespace, and lifecycle_stage aren’t self-reported in a production deployment. Instead, the evaluator retrieves these attributes from the Verified Permissions entity store using the agent_id as a lookup key.

Important: The reference implementation accepts these values from the request payload for simplicity. Production deployments must validate agent attributes against an authoritative source to prevent a compromised agent from escalating its own trust.

The trust_level attribute uses a 1–5 integer scale that represents an agent’s verified maturity: 1 for newly registered and untested agents, 3 for agents that have passed integration testing and security review, and 5 for agents with a proven production track record. Organizations assign trust levels through their agent promotion pipeline, not through self-declaration. The lifecycle_stage attribute (development, staging, production) prevents pre-production agents from invoking production tools, even if they have the correct namespace and trust score.

// L1-001: Finance agent can invoke payment tools
permit(
  principal == AgentAuthz::Agent::"finance-agent",
  action == AgentAuthz::Action::"invoke_tool",
  resource == AgentAuthz::Tool::"process_payment"
) when {
  principal.trust_level >= 3 &&
  principal.namespace == "payments" &&
  principal.lifecycle_stage == "production"
};

Layer 2 (agent-to-agent delegation) enforces depth limits and capability constraints. The orchestrator agent delegates tasks to data-bot only when the delegation chain is three hops or fewer and the requested capabilities are a subset of data-bot’s registered capabilities. A separate forbid policy (L2-004) enforces a hard system-wide limit of five hops regardless of which agents are involved.

// L2-002: Orchestrator can delegate to data agent
permit(
  principal == AgentAuthz::Agent::"orchestrator",
  action == AgentAuthz::Action::"delegate_task",
  resource == AgentAuthz::Agent::"data-bot"
) when {
  context.delegation_depth <= 3 &&
  context.target_capabilities.containsAll(context.requested_capabilities)
};

Layer 3 (originating user authorization) keeps the agent as the principal, but the policy evaluates context.originating_user to validate the human who initiated the request. data-bot invokes the delete_records tool only when the originating user has the admin role, has verified MFA, and the delegation chain is at most two hops deep. Without this layer, an agent with the right capabilities could invoke destructive tools regardless of who initiated the request.

// L3-001: High-risk tool (delete_records) requires admin + MFA
permit(
  principal == AgentAuthz::Agent::"data-bot",
  action == AgentAuthz::Action::"invoke_tool",
  resource == AgentAuthz::Tool::"delete_records"
) when {
  context.originating_user.role == "admin" &&
  context.originating_user.mfa_verified == true &&
  context.delegation_depth <= 2
};

Key design point: The principal remains the agent, not a user entity. The user’s role and MFA status are checked through context attributes, keeping the schema to two entity types and two actions.

Integrate your IdP

The reference implementation uses Amazon Cognito with TOTP MFA, but most OIDC-compliant providers (Okta, Microsoft Entra ID, Auth0, or AWS IAM Identity Center) work with this pattern. The authentication-to-signing flow is described in the preceding Authentication before authorization section. To use a different IdP, replace the Cognito authorizer on API Gateway with a Lambda or JWT authorizer for your IdP’s issuer URL. Cedar policies remain unchanged.

Deploy the infrastructure with AWS CDK

The reference implementation deploys five CloudFormation stacks: KmsStack, VerifiedPermissionsStack, LambdaStack, SecurityLakeStack, and MonitoringStack. The following commands deploy the stacks in dependency order:

cdk deploy KmsStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID
cdk deploy VerifiedPermissionsStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID
cdk deploy LambdaStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID
cdk deploy SecurityLakeStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID
cdk deploy MonitoringStack -c account_id=YOUR_ACCOUNT_ID -c guardrail_id=YOUR_GUARDRAIL_ID

Test the solution

Three end-to-end scenarios validate the evaluation model across different user roles, MFA states, and delegation depths. To run the tests:

  1. Set the API endpoint from the deployment output:
export API_ENDPOINT=$(aws cloudformation describe-stacks --stack-name LambdaStack \
  --query "Stacks[0].Outputs[?OutputKey=='ApiEndpoint'].OutputValue" --output text)

  1. Run the end-to-end tests:
.venv/bin/python -m pytest tests/e2e/ -v -s

The end-to-end tests cover the three scenarios described in the following sections. Each test sends a request through the deployed API and validates the per-layer authorization decisions.

Scenario A: Layer 3 enforcement

A support-role user (no MFA) requests record deletion through orchestrator and data-bot.

Layer Decision Reason
L1: Agent-to-tool PERMIT data-bot has trust level 4, namespace data, and lifecycle production
L2: Agent-to-agent PERMIT orchestrator is authorized to delegate to data-bot, depth within limits
L3: Originating user DENY User role is support, not admin; MFA not verified
Overall DENY Denying layer: L3

Without Layer 3, this request would have been permitted based on agent capabilities alone, demonstrating why originating user authorization is essential.

Scenario B: Authorized admin request

An admin user with MFA requests the same operation through the same chain.

Layer Decision Reason
L1 PERMIT Agent attributes match
L2 PERMIT Delegation path authorized
L3 PERMIT Role is admin, MFA verified, depth is less than or equal to 2
Overall PERMIT All three layers permit

Scenario C: Delegation depth limit

An admin with MFA requests the same operation, but the delegation chain has six hops. This scenario tests the Layer 2 depth constraint independently of user authorization.

Layer Decision Reason
L1 PERMIT Agent attributes match
L2 DENY Depth of six exceeds the hard limit of five
Overall DENY Denying layer: L2 (L3 not evaluated – halt)

Even an authorized admin can’t bypass the delegation depth constraint.

Alignment with the security principles for agentic AI

The AWS Office of the CISO published Four security principles for agentic AI systems. The following table shows how this solution maps to each principle.

Principle How the solution implements it
Secure development lifecycle across components Property-based testing (Hypothesis) for adversarial input fuzzing, Cedar policy formal verification with strict schema validation, end-to-end scenarios testing policy bypass and privilege escalation paths, and infrastructure-as-code (IaC) with AWS CDK.
Traditional security controls remain applicable AWS WAF, Amazon VPC isolation, AWS Key Management Service (AWS KMS) encryption, Amazon Cognito MFA, and Secrets Manager;
NIST SP 800-53 control mapping.
Deterministic external controls (security box) Three-layer Cedar evaluation runs outside the agent’s reasoning loop in a separate Lambda function.
HMAC-signed context prevents tampering.
Verified Permissions (the managed Cedar evaluation service) enforces L2 and L3 at the infrastructure level.
Greater autonomy earned through evaluation trust_level and lifecycle_stage policy attributes calibrate agent capabilities; OCSF 99001 audit events and Amazon CloudWatch dashboards provide the evidence base for expanding autonomy.

Monitoring and audit compliance

Each evaluation produces an OCSF 99001 audit event with request ID, user identity, delegation chain, per-layer decisions, and latency.

The following table maps this implementation to NIST SP 800-53 Rev. 5 controls. Customers are responsible for evaluating whether it meets their compliance requirements.

NIST control Control name How the reference implementation addresses it
AC-4 Information Flow Enforcement User context flows immutably through HMAC-signed envelopes
AC-6 Least Privilege Three-layer evaluation requires both agent capability and user role
AC-6(1) Authorize Access to Security Functions MFA required for high-risk tools in Layer 3
AC-6(5) Privileged Accounts Destructive operations restricted to admin with MFA verified
AU-2 Event Logging Each evaluation is logged as OCSF 99001
AU-3 Content of Audit Records Events include identity, chain, action, resource, decisions, and latency
SI-10 Information Input Validation HMAC verified before evaluation; Amazon Bedrock Guardrails on inbound
IA-2(1) Multi-factor Authentication Layer 3 enforces MFA for high-risk operations
SC-12 Cryptographic Key Management Signing key in Secrets Manager with rotation
SC-28 Protection of Information at Rest Policies in Verified Permissions with STRICT validation

Scaling to multi-account environments

Deploy the Cedar policy store in a central security account and use cross-account IAM roles for workload accounts to call verifiedpermissions:IsAuthorized. Use AWS Organizations service control policies (SCPs) to prevent workload accounts from creating their own policy stores. For standardizing user identity attributes across the organization, consider IAM Identity Center or a centralized OIDC provider that issues consistent claims to your workload accounts. This helps ensure that the context.originating_user attributes are uniform across accounts and agents.

For production deployments, consider extending this pattern with human-in-the-loop escalation for borderline denials, multi-tenant Cedar policy isolation, and Amazon Simple Storage Service (Amazon S3)-backed dynamic policy hot-reload for emergency tool shutdowns.

Clean up

To avoid ongoing charges, delete the deployed resources:

cdk destroy MonitoringStack SecurityLakeStack
cdk destroy LambdaStack
cdk destroy VerifiedPermissionsStack
cdk destroy KmsStack
aws logs delete-log-group --log-group-name /cedar-evaluator/audit  # if RETAIN policy

Conclusion

Multi-agent AI systems need authorization boundaries at every delegation hop. The three-layer Cedar policy model with OAuth 2.0 authentication provides that protection while maintaining least-privilege access. Combining a trusted IdP (AuthN) with Cedar policy evaluation (AuthZ) creates an authorization boundary around each tool invocation, verifying agent capability (L1), delegation path (L2), and originating user authority (L3). The pattern works with an OIDC-compliant IdP and a compute platform that can call Amazon Verified Permissions. Clone the reference implementation and adapt the Cedar policies to your organization’s requirements. For more information, see the Cedar policy language documentation and the Amazon Verified Permissions User Guide.

References

If you have feedback about this post, submit comments in the Comments section below.


Dhananjay Karanjkar

Dhananjay Karanjkar

Dhananjay is a Senior Lead Consultant at AWS Professional Services, specializing in agentic AI systems, multi-agent orchestration, and generative AI security. He holds two US patents and serves as a Responsible AI Champion, with a background spanning financial services, enterprise consulting, and enterprise-scale AI delivery. When not architecting AI solutions, he trains for triathlons, paints oil portraits, and is an avid reader.

Secure Amazon container workloads using container attribute-based rules in AWS Network Firewall

Post Syndicated from Amit Gaur original https://aws.amazon.com/blogs/security/secure-amazon-container-workloads-using-container-attribute-based-rules-in-aws-network-firewall/

Today, you can use AWS Network Firewall to protect traffic flowing to and from containerized applications on Amazon Elastic Kubernetes Service (Amazon EKS) and Amazon Elastic Container Service (Amazon ECS) clusters. If you run AI and machine learning (ML) workloads on Amazon EKS—such as model inference, RAG pipelines, or JupyterHub—your containerized workloads require the same firewall protections you enforce for traditional applications. However, traditional firewall rules rely on IP addresses, and pod IPs in Kubernetes change frequently as containers scale or restart. Writing and maintaining static firewall rules based on these ephemeral IPs, CIDRs, and subnets is difficult and error-prone, which can leave gaps in your security posture.

Kubernetes Network Policies offer basic traffic control at the namespace level, operating at layers 3 and 4. Depending on your security requirements, you might need additional capabilities beyond what network policies provide: Layer 7 inspection, FQDN-based filtering, and protection from threats detected by managed IDS/IPS rules. Visibility into which pod or service generates blocked traffic is equally important, so you can troubleshoot faster and meet audit requirements.

You can use container attribute-based rules for Network Firewall to define firewall rules for your containerized workloads on both Amazon EKS and Amazon ECS using native container attributes, rather than relying on ephemeral IP addresses. For Amazon EKS, these attributes include namespaces, pod names, cluster names, and labels. This reduces the need to maintain IP-based rules in dynamic container environments. While this capability supports both Amazon EKS and Amazon ECS, this post focuses on Amazon EKS. Your containerized workloads get the same Network Firewall capabilities you use today.

There is no additional charge for the feature itself, because it’s included in the base tier of Network Firewall.

How it works

When you create a container association and link it to your EKS cluster, Network Firewall automatically discovers and tracks the pods that match your defined attributes (namespace, labels, cluster name) and resolves them to their current IP addresses. As pods scale up or restart, the firewall dynamically updates the IP-to-attribute mapping in near real-time and no manual rule updates are required. This approach keeps your firewall rules accurate in dynamic environments while minimizing performance impact on the EKS cluster. In multi-cluster environments, this feature enables centralized cross-cluster traffic inspection for any traffic that passes through the firewall.

Container attribute-based rules also enrich firewall alert logs with container context. Alert logs now include a new metadata field with the container association name associated with the matched rule. This gives security teams the ability to trace blocked, allowed, or alerted traffic directly back to the originating workload. Network Firewall exports these enriched logs to Amazon CloudWatch Logs and Amazon Simple Storage Service (Amazon S3), from where you can forward them to the SIEM of your choice. To bind these attribute groups to running workloads, Network Firewall continuously watches your EKS cluster for pod lifecycle events (create and delete) across the namespaces covered by your container association definition. This definition is stored in a container association, keyed by attribute name and value.

When published, you reference these @ aliases in stateful Suricata rules. The following are some common patterns:

  • Pod group rules: Allow only payment-service pods to reach the external payment gateway over TLS:
    pass tls @ecommerce_pods any -> any 443 (msg:"allow ecommerce to payment gateway"; tls.sni; content:“checkip.amazonaws.com”; flow:to_server,established; sid:1; rev:1;)

  • Layer 7 application rules : Enforce block from all pods from reaching malicious destinations:
    drop tls @all-pods any -> $EXTERNAL_NET any (msg:"Block malicious sites"; aws_domain_category:malicious-sites; sid:10; rev:1;)

At packet evaluation time, Network Firewall expands each @ reference against the current catalog. When pods scale, restart, or move between nodes, the controller refreshes group membership, and the firewall picks up the new IPs, hence no rule edits or operator intervention is required. Each match—whether alert, pass, or drop—streams to the logging destination of your choice with container context. This gives your team a real-time, auditable view of policy effectiveness and a feedback loop for tuning rules and pod-group definitions over time.

Getting started

The Network Firewall container attribute-based rules for Amazon container workloads can be configured using the AWS Management Console for Amazon Virtual Private Cloud (Amazon VPC), AWS Command Line Interface (AWS CLI), or AWS SDK by creating a container association. This container association then can be used to create attribute-based Network Firewall rules.

Prerequisites

This walkthrough requires an existing Network Firewall configured to filter traffic through your Amazon VPC. If you haven’t set one up yet, see Getting started with AWS Network Firewall.

Step 1 – Create a container association:

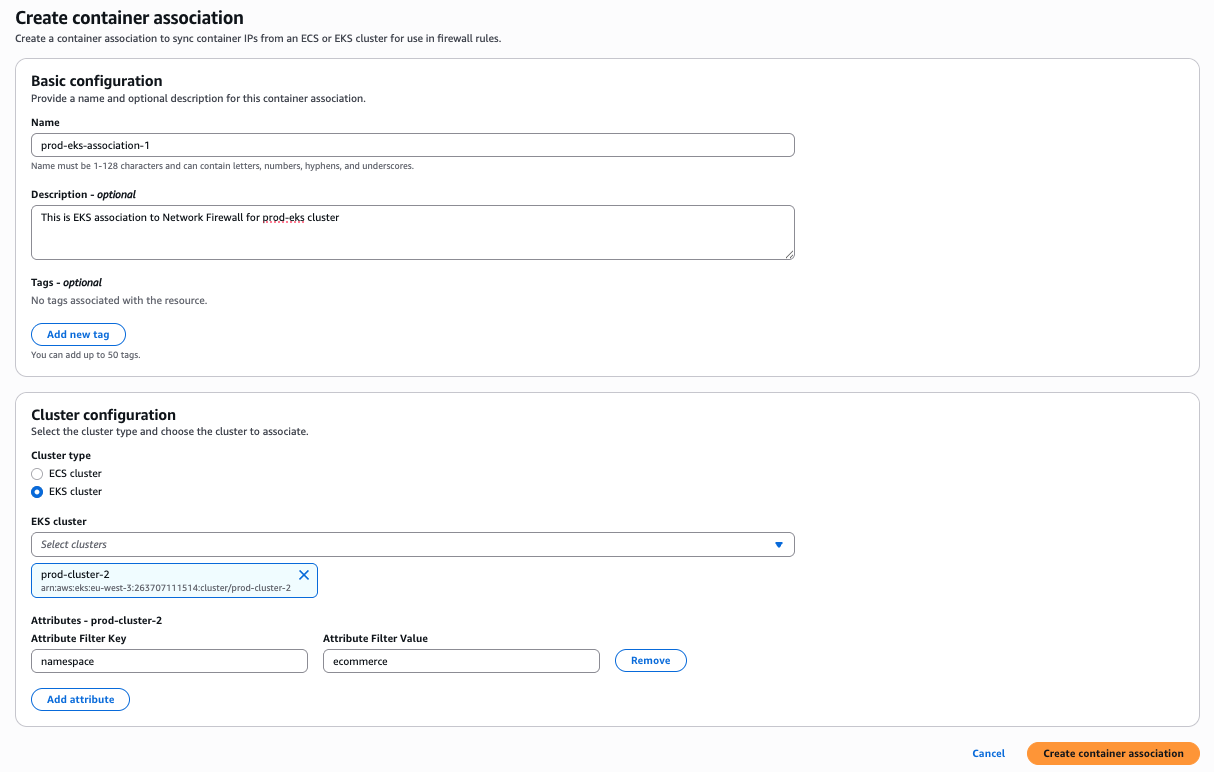
  1. In the AWS VPC console, navigate to Network Firewall, select Container associations. Choose Create container association.
  2. Enter a Name and optional Description for this container association.
  3. Under Cluster configuration, select the Cluster type and select your EKS cluster from the Cluster drop down.
  4. For Attribute filters, configure the EKS attribute to identify which pods to associate:
    • Attribute key: Enter the attribute key defined in your EKS cluster (for example, namespace, pod, cluster, or custom label key).
    • Attribute value: Enter an attribute key value defined in your EKS cluster.
Figure 1: Create container association

Figure 1: Create container association

Step 2 – Create an attribute-based firewall rule:

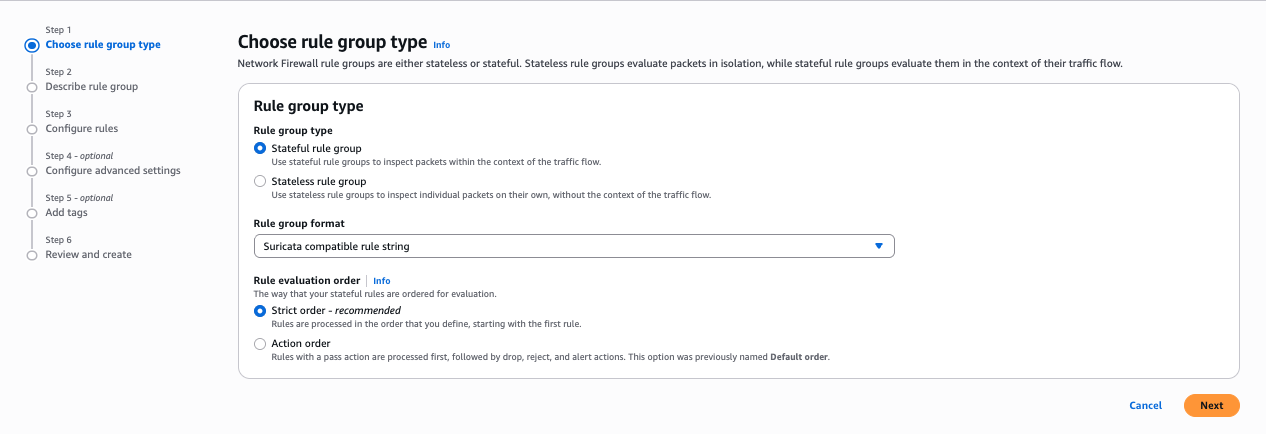
  1. In the AWS VPC console, navigate to Network Firewall, then select Network Firewall rule groups.
  2. Select Create rule group.
  3. For Rule group type, select Stateful rule group.
  4. For Rule group format, select Suricata compatible rule string.
    Figure 2: Rule group selection

    Figure 2: Rule group selection

  5. For Rule evaluation order, select Strict order. Choose Next.
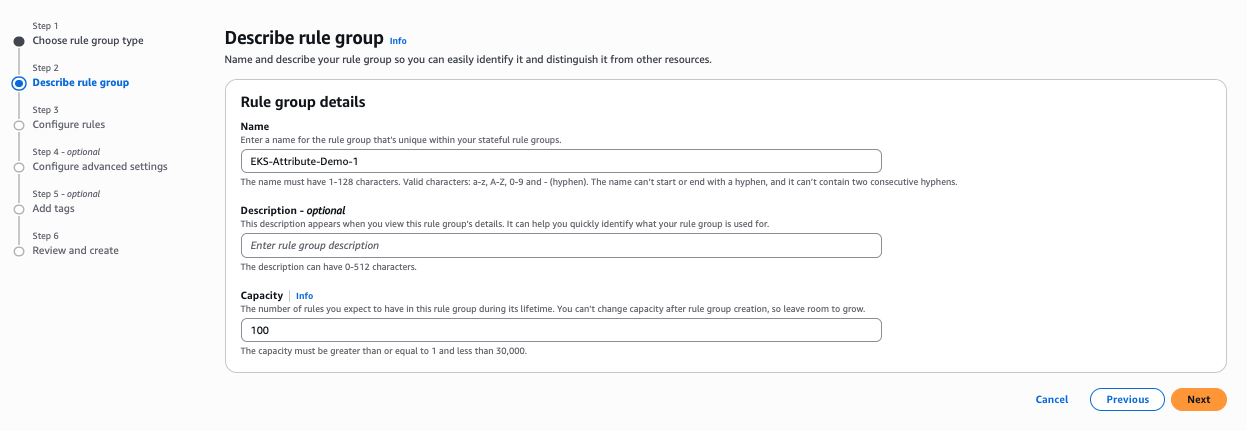
  6. Under Describe rule group, enter a Name, Description, and Capacity for the rule group. Choose Next.
    Figure 3: Describe rule group

    Figure 3: Describe rule group

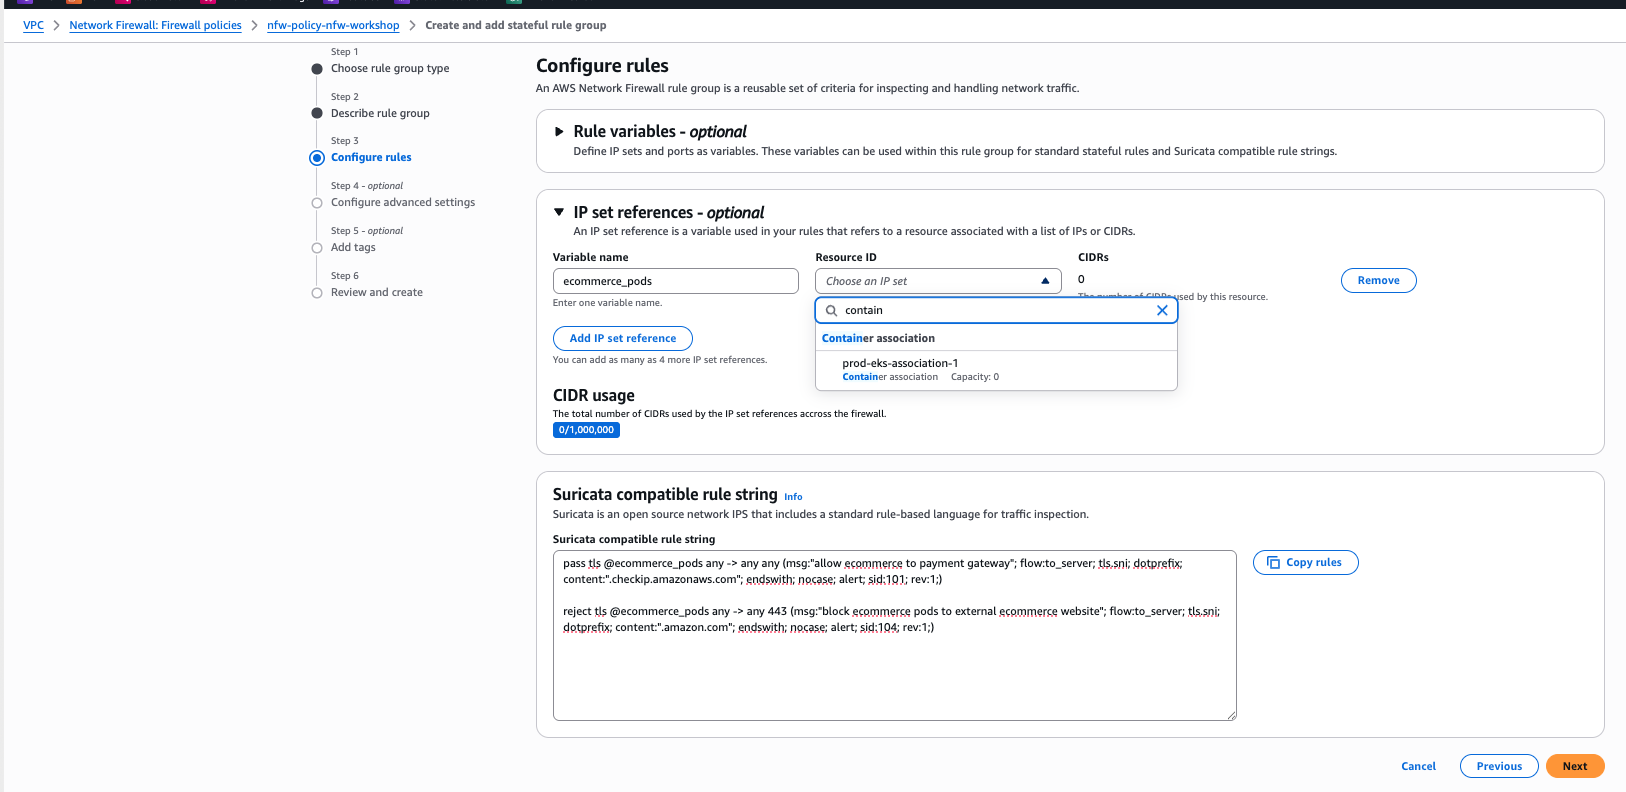
  7. Under IP set references, enter a variable name and from the resource ID drop-down, select the container association created in step 1.
  8. Under Suricata compatible rule string, enter your Suricata rule string. The following is a sample string used for this post:
    pass tls @ecommerce_pods any -> any any (msg:"allow ecommerce to payment gateway"; flow:to_server; tls.sni; dotprefix; content:".checkip.amazonaws.com"; endswith; nocase; alert; sid:101; rev:1;)
    
    reject tls @ecommerce_pods any -> any 443 (msg:"block ecommerce pods to external ecommerce website"; flow:to_server; tls.sni; dotprefix; content:".amazon.com"; endswith; nocase; alert; sid:104; rev:1;)

    Figure 4: Configure rules

    Figure 4: Configure rules

  9. Choose Next.
  10. Enter the details if required on the next options. For this post, we’re using the default values.
  11. On the review and create page, choose Create rule group.

Tests and results

To verify these rules are working as expected, test using the curl command on a pod in the ecommerce namespace. A curl request to www.amazon.comshould fail, because action=rejectis defined in the Suricata rule string. Similarly, a request to the payment gateway URL should succeed, because action=passis defined in the Suricata rule string.

Test 1 – Allowed traffic:

kubectl exec -n ecommerce deployment/payment-service -- curl -sk --max-time 5 -w "\nHTTP_CODE:%{http_code}\n" https://checkip.amazonaws.com/

HTTP_CODE:200

Test 2 – Blocked traffic:

kubectl exec -n ecommerce deployment/payment-service -- curl -sk --max-time 5 https://www.amazon.com 2>&1

curl: (35) Recv failure: Connection reset by peer
command terminated with exit code 35

Container association can also be used in a Standard stateful rules format.

Considerations

There are several important considerations when adopting this feature.

  1. Source NAT (SNAT) must be disabled so that the Network Firewall can see pod IP addresses. If SNAT remains enabled, only the node IP will be visible, preventing granular pod-level egress controls.
  2. This feature can’t enforce security on pod-to-pod traffic within the same node, because that traffic doesn’t traverse the Network Firewall endpoint. A separate solution is needed for this use case.
  3. Performance impact can vary based on rule complexity and traffic volume.

Conclusion

In this post, you learned how container attribute-based rules for AWS Network Firewall solve the challenge of securing dynamic containerized workloads. You explored how the feature maps Kubernetes attributes such as namespaces, pod names, cluster names, and labels to firewall rules, eliminating the need to track ephemeral IP addresses. You walked through how to create a container association to link your EKS cluster attributes to Network Firewall, and then how to reference that association using IP set references in Suricata compatible rule strings. This gives you granular traffic control of your Amazon EKS workloads with the same Network Firewall capabilities as traditional applications including layer 7 inspection, FQDN filtering, TLS decryption, and managed IDS/IPS rules along with enriched logging that traces traffic back to the originating workload.

If you have feedback about this post, submit comments in the Comments section below.


Amit Gaur

Amit Gaur

Amit, a Cloud Infrastructure Architect at AWS, brings his passion for technology and knowledge-sharing to the networking community. Specializing in network architecture design, he helps customers build highly scalable and resilient environments on AWS. Through technical guidance and architectural expertise, Amit enables customers to accelerate their cloud adoption journey while making sure their systems are built for scale and reliability.

Preetkumar Shah

Preetkumar Shah

Preetkumar is a Technical Account Manager at AWS, based in Atlanta, GA. He specializes in helping customers design and operate secure, scalable network architectures in the cloud. At AWS, he works with SMB customers and collaborates closely with service teams to proactively resolve complex challenges and ensure customers get the most from their AWS environment. Outside of work, his interests include spending time with family and going on trails.

Akash Kuman Sinha

Akash Kumar Sinha

Akash is a DevOps Consultant and GenAI Ambassador at AWS, where he helps customers transform their cloud operations through containerization and modern delivery practices. He specializes in container orchestration and DevOps automation, and is a regular speaker at AWS events across Europe. Outside of work, Akash is passionate about knowledge-sharing and exploring the intersection of generative AI and cloud-native innovation.

Amish Shah

Amish is a seasoned product leader with over 15 years of experience in developing innovative and scalable solutions for networking, security, and cloud use cases. He currently leads the AWS Network Firewall service, where he helps to develop security solutions that protect AWS workloads. Outside of work, Amish enjoys playing cricket and soccer, loves to travel, and has recently started collecting niche fragrances.

How to use the AWS Workload Credentials Provider for cross-account secret retrieval and prefetching secrets

Post Syndicated from Derik Wang original https://aws.amazon.com/blogs/security/how-to-use-the-aws-workload-credentials-provider-for-cross-account-secret-retrieval-and-prefetching-secrets/

If you manage secrets across multiple AWS accounts or need faster secret access for latency-sensitive applications, this post shows you how to meet those requirements using two new features of the AWS Workload Credentials Provider (provider). You will learn how to configure role chaining for cross-account secret retrieval and prefetching of secrets to reduce cold-start latency.

By using role chaining, you can access secrets across AWS accounts through a single provider instance by assuming AWS Identity and Access Management (IAM) roles. Prefetching populates the provider’s in-memory cache with secrets at startup so your application can retrieve secrets without waiting for the first request to trigger a network call at runtime.

What is the AWS Workload Credentials Provider?

AWS Secrets Manager stores and rotates credentials, API keys, and other secrets. The AWS Workload Credentials Provider is a client-side HTTP service that retrieves and caches secrets locally. This reduces latency, improves availability during transient failures, and lowers costs. It supports post-quantum TLS by default, requires no language-specific SDK, and works across Amazon Elastic Compute Cloud (Amazon EC2), Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), and AWS Lambda. For more details, see the Workload Credentials Provider documentation and GitHub repository.

Security considerations

The Server-Side Requst Forger (SSRF) token prevents unauthorized processes from accessing the provider’s HTTP endpoint. Only applications that can read the token file can retrieve secrets through the provider.

Any identity that can access the provider’s endpoint and SSRF token can retrieve secrets through role chaining. This means users with compute environment access can retrieve cross-account secrets when role assumption is configured. Scope the target role’s permissions to only the secrets required by following the principle of least privilege.

For prefetching, secrets are loaded into the provider’s in-memory cache at startup. Any process that can reach the provider’s localhost endpoint and provide a valid SSRF token can retrieve prefetched secrets from the cache.

Cross-account secret retrieval with role chaining

Organizations might store secrets in a dedicated AWS account, or need to share one secret across applications in different accounts. Until now, cross-account retrieval through the provider required attaching resource-based policies directly to each secret. Some customers prefer IAM role assumption. Before this feature, you had to deploy multiple provider instances with different credentials or build custom credential-switching logic. The provider now supports both approaches: resource-based policies and IAM role assumption. While role assumption is especially useful for cross-account scenarios, it also helps within the same account when secrets are protected by different customer-managed KMS keys.

When you include the roleArn query parameter in a request, the provider uses AWS Security Token Service (AWS STS) AssumeRole to obtain temporary credentials for the specified role and retrieves the secret with those credentials. The provider creates and caches a separate client for each role ARN, so subsequent requests to the same role reuse the existing client. Each role client maintains its own independent cache.

Note: The source account runs the Workload Credentials Provider and your application. The target account contains the secret you want to retrieve. A single provider instance in the source account can assume roles in one or more target accounts.

Prerequisites

  • A Workload Credentials Provider built and installed in your environment (see the README for build instructions)
  • AWS credentials configured in your compute environment with permission to call sts:AssumeRole on the target role ARN
    • If you also retrieve secrets from the source account through the provider, the credentials need secretsmanager:GetSecretValue and secretsmanager:DescribeSecret permissions for those secrets
  • A secret in a target AWS account that you want to retrieve
  • An IAM role in the target account with a trust policy that allows the provider’s identity to assume it

To build the Workload Credentials Provider

The provider is written in Rust and compiles to a single executable. The following steps are for an RPM-based system such as Amazon Linux 2023:

  1. Install build dependencies:
    sudo yum -y groupinstall "Development Tools"

  2. Install Rust:
    curl --proto '=https' --tlsv1.2 -sSf https://sh.rustup.rs | sh
    source "$HOME/.cargo/env"

  3. Clone the repository and build the provider (use the latest tag available):
    git clone --branch <git tag> https://github.com/aws/aws-workload-credentials-provider.git
    cd aws-workload-credentials-provider
    cargo build --release

The compiled binary is at target/release/aws-workload-credentials-provider.

To install the Workload Credentials Provider on Amazon EC2

After building the provider, install it as a system service on your EC2 instance and configure access to the SSRF token.

  1. After configuring your config.toml file (see Configuration options section), run the install script to deploy the provider as a systemd service and generate the SSRF token:
    cd aws_workload_credentials_provider_common/configuration
    sudo ./install --config config.toml

  2. Add your application user to the aws-wcp-token group. This grants your application permission to read the SSRF token file, which is required for all secret retrieval requests:
    sudo usermod -aG aws-wcp-token <APP_USER>

To install on Amazon ECS, Amazon EKS, or Lambda, see the installation instructions in the GitHub repository.

To verify the installation

  1. Check that the provider is running:
    curl -v -H \
        "X-Aws-Parameters-Secrets-Token: $(</var/run/awssmatoken)" \
        'http://localhost:2773/secretsmanager/get?secretId=<YOUR_SECRET_ID>'

  2. You’ll receive a JSON response with the secret value. If you see a connection refused error, check that the provider process is running. If you see a 401 or 403 error, verify the SSRF token file is readable and that the provider’s IAM credentials have secretsmanager:GetSecretValue and secretsmanager:DescribeSecret permissions.

Required permissions

The provider’s base IAM identity requires:

  • sts:AssumeRole on the target role ARN

The target role requires:

  • secretsmanager:GetSecretValue
  • secretsmanager:DescribeSecret

To configure the target account IAM role

Create an IAM role in the target account with a trust policy that allows the provider’s identity in the source account to assume it. Then attach a policy that grants access to the required secrets.

  1. Create an IAM role in the target account with a trust policy that allows the provider’s identity in the source account to assume it.
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Principal": {
                    "AWS": "arn:aws:iam::111111111111:role/WCProviderRole"
                },
                "Action": "sts:AssumeRole"
            }
        ]
    }
    

  2. Attach a policy to this role that grants access to the secret:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "secretsmanager:GetSecretValue",
                "secretsmanager:DescribeSecret"
            ],
            "Resource": "arn:aws:secretsmanager:us-east-1:222222222222:secret:MyDatabaseSecret"
        }
    ]
}

To configure the source account IAM role

Before the provider can assume the role you created in the target account, grant it permission to call sts:AssumeRole. Attach the following policy to the provider’s IAM role in the source account:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": "sts:AssumeRole",
            "Resource": "arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole"
        }
    ]
}

To retrieve the cross-account secret

Call the Workload Credentials Provider endpoint with the roleArn parameter. The following curl example shows how to retrieve a secret using a different IAM role:

curl -v -H "X-Aws-Parameters-Secrets-Token: $(</var/run/awssmatoken)" 'http://localhost:2773/secretsmanager/get?secretId=MyDatabaseSecret&roleArn=arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole'

The following Python example shows the same operation:

import requests

def get_secret_cross_account():
    role_arn = "arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole"
    url = f"http://localhost:2773/secretsmanager/get?secretId=MyDatabaseSecret&roleArn={role_arn}"

    with open('/var/run/awssmatoken') as fp:
        token = fp.read()

    headers = {
        "X-Aws-Parameters-Secrets-Token": token.strip()
    }

    response = requests.get(url, headers=headers)

    if response.status_code == 200:
        return response.text
    else:
        raise Exception(f"Status code {response.status_code} - {response.text}")

You can configure the maximum number of simultaneous assumed roles with the max_roles option in the provider’s TOML configuration file. The default is 20, and the range is 1–20.

Prefetching secrets at startup

By default, the Workload Credentials Provider populates its cache lazily—the first request for a secret triggers a network call to Secrets Manager. Prefetching reduces this cold-start latency by loading secrets at startup.

How prefetching works

You can configure prefetching by adding a [capabilities.secrets_manager.prefetch] section to the provider’s TOML configuration file. You can specify secrets to prefetch in two ways:

  • Explicit secrets – List specific secret IDs or ARNs using [[capabilities.secrets_manager.prefetch.secrets]] entries.
  • Tag-based discovery – Discover secrets by tag key using [[capabilities.secrets_manager.prefetch.filter_tags]] entries. The provider calls BatchGetSecretValue with tag key filters to find and cache all matching secrets.

You can use both methods together. Each entry optionally accepts a role_arn field for cross-account prefetching through role chaining.

Required permissions

The following permissions are required on the IAM role that performs the prefetch, depending on whether the secrets are in the source account or a target account.

  • secretsmanager:BatchGetSecretValue – Required on the source account role for source-account secrets, or on the target role for cross-account secrets
  • secretsmanager:ListSecrets – Required when using tag-based discovery (filter_tags), on whichever role is performing the discovery

Configuration options

You can tune prefetch behavior with the following options in the [capabilities.secrets_manager.prefetch] section of your TOML configuration file:

  • cache_buffer_ratio – The maximum fraction of the cache to fill per caching client during prefetch, in the range 0.1–1.0. The default is 0.8. For example, if your cache holds 100 secrets, a ratio of 0.8 prefetches up to 80, leaving room for 20 on-demand secrets to be cached.
  • max_jitter_seconds – The maximum random delay in seconds before starting the prefetch task, in the range 0–10. The default is 0 (no jitter). Use this to prevent fleet-wide synchronized API calls when deploying across many instances.

Example: Prefetch with explicit secrets

The following configuration prefetches two secrets at startup, one from the source account and one from a different account using role chaining:

[capabilities.secrets_manager.prefetch]
secrets = [
    { secret_id = "arn:aws:secretsmanager:us-east-1:111111111111:secret:MySecret-AbCdEf" },
    { secret_id = "cross-account-secret", role_arn = "arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole" }
]

Example: Prefetch with tag-based discovery

The following configuration discovers and caches all secrets tagged with the Environment key, and all secrets tagged with the Team key in a different account:

[capabilities.secrets_manager.prefetch]
filter_tags = [
    { key = "Environment" },
    { key = "Team", role_arn = "arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole" },
]

Example: Full configuration

The following example shows a complete provider configuration that combines both features:

[logging]
log_level = "info"

[capabilities.secrets_manager]
http_port = 2773
region = "us-east-1"

[capabilities.secrets_manager.cache]
ttl_seconds = 300

[capabilities.secrets_manager.prefetch]
cache_buffer_ratio = 0.6
max_jitter_seconds = 5
secrets = [
    { secret_id = "arn:aws:secretsmanager:us-east-1:111111111111:secret:MySecret-AbCdEf" },
    { secret_id = "arn:aws:secretsmanager:us-east-1:222222222222:secret:CrossAccount-AbCdEf", role_arn = "arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole" },
]
filter_tags = [
    { key = "Environment" },
    { key = "Team", role_arn = "arn:aws:iam::222222222222:role/CrossAccountSecretAccessRole" },
]

Start the provider with your configuration file:

./aws-workload-credentials-provider sm start --config config.toml

Conclusion

This post showed you how to use role chaining for cross-account secret retrieval and prefetching to reduce cold-start latency. Role chaining simplifies multi-account architectures—a single provider instance can retrieve secrets across accounts using IAM role assumption. Prefetching reduces cold-start latency by populating the provider’s cache before your application makes its first request. Combined, these features let you run the Workload Credentials Provider across multiple accounts with faster secret access.

Further reading

Submit feedback in the comments below, or contact AWS Support with questions.


Derik Wang

Derik Wang

Derik is a Software Engineer on the AWS Secrets Manager team.

Paras Dhawan

Paras Dhawan

Paras is a Software Development Manager for AWS Secrets Manager, based in Seattle. Paras joined AWS in 2017 and has spent his career across AWS Identity, AWS Cryptography, and Credentials Distribution Systems. He is passionate to innovate, solve and simplify customer problems related to security, access, authorization and beyond.

What the June 2026 Threat Technique Catalog update means for your AWS environment

Post Syndicated from Shannon Brazil original https://aws.amazon.com/blogs/security/what-the-june-2026-threat-technique-catalog-update-means-for-your-aws-environment/

The AWS Customer Incident Response Team (AWS CIRT) encounters patterns that repeat across engagements when helping customers respond to security incidents. We’re passionate about making sure that information is accessible so that everyone can improve their security posture and their organization’s resilience to disruption. The primary method we use to share this information is the Threat Technique Catalog for AWS (TTC). The latest update to the catalog for June 2026 focuses on container security, organization-level trust, and compute hijacking. Each new entry reflects something we’ve encountered in practice, and each provides straightforward mitigation. This post breaks down what changed, why it matters, and what you can do about it today.

What we’re seeing

We’ve added five new entries to the TTC.

EKS workload modification

Amazon Elastic Kubernetes Service (Amazon EKS) gives teams powerful orchestration capabilities. We’re seeing threat actors who have obtained Kubernetes credentials or an AWS Identity and Access Management (IAM) role with EKS permissions modify running workloads—altering container images, injecting sidecar containers, or changing pod specifications to introduce malicious code into a deployment.

Nothing new is created. The workload already exists, it might be running in production, and by modifying it in place the threat actor inherits the network access, service account permissions, and data access the legitimate workload already had. Without admission controllers or image verification, these changes can go unnoticed until the impact shows up downstream. Enforcing image signing through admission controllers, restricting workload changes with Kubernetes role-based access control (RBAC), and enabling Amazon GuardDuty EKS Protection to surface anomalous cluster activity all reduce this risk. For more information, see EKS Modification – Workload Integrity Degradation.

Exploit public-facing application – EKS

Publicly exposed Kubernetes API servers and misconfigured ingress controllers continue to be an entry point we see exploited. This technique captures threat actors targeting the customer-deployed workloads running on Amazon EKS—not EKS itself—and their exposure to the internet.

The pattern starts with an exposed service and an application-level weakness, then pivots from the compromised pod toward broader cluster access. When inside a pod, a threat actor can query the instance metadata service, read mounted service account tokens, or move laterally across the cluster network. Limiting public exposure of the Kubernetes API server, applying network policies to restrict pod-to-pod communication, and running workloads with least-privilege service accounts reduce the risk of this technique succeeding. For more information about this technique, see Exploit Public-Facing Application.

Assume root into organization member account

AWS Organizations centralizes trust across member accounts, and that trust runs in one direction—from the management account downward. We’ve observed threat actors who compromise a management account—or gain sufficient privilege within one—use that position to assume root access into member accounts using sts:AssumeRoot. Because the trust is inherent to the organization structure, this can avoid the access controls a member account administrator has configured.

With root access to a member account, a threat actor can disable security controls, delete resources, change billing configurations, and establish persistence that survives remediation focused on IAM principals. We strongly encourage implementing service control policies (SCPs) that restrict which principals can call sts:AssumeRoot and under what conditions, and monitoring for sts:AssumeRoot calls in AWS CloudTrail. For more information, see Assume Root into Organization Member Account.

Compute hijacking – EKS

Compute hijacking remains one of the most common motivations we see behind unauthorized access, and Amazon EKS clusters are increasingly the target. Threat actors deploy cryptocurrency mining or other compute-intensive workloads inside compromised clusters, consuming customer resources and generating unexpected cost.

What sets EKS-based hijacking apart is scale. In clusters without resource quotas, a single compromised service account can consume all available capacity across nodes. The workloads use legitimate-looking images pulled from public registries, which makes image scanning alone insufficient. Setting resource quotas and limit ranges, restricting which registries workloads can pull from, and enabling Amazon GuardDuty EKS Protection to flag mining behavior provides effective detection. For more information, see Resource Hijacking: Compute Hijacking – EKS.

Invite accounts to unknown organization

A threat actor with access to a standalone account—or one they’ve removed from its legitimate organization—invites it into an organization they control. After the account joins, it falls under the threat actor’s governance. The threat actor’s organization can apply SCPs that restrict the legitimate owner’s actions, gain visibility into the account’s resources through organizational services, and access consolidated billing information. The legitimate owner finds themselves locked out of their own governance controls. Monitoring organizations:InviteAccountToOrganization and organizations:AcceptHandshake, and implementing SCPs that prevent accounts from leaving their legitimate organization are important preventive measures. For more information, see Modify Cloud Resource Hierarchy: Invite Accounts to Unknown Organization.

What’s updated

We’ve refreshed three existing entries. S3 Object Collection now captures additional API calls used for bulk data staging from Amazon Simple Storage Service (Amazon S3), with refined detection guidance and mitigations that use recent Amazon S3 security features. Compute Hijacking – ECS adds methods threat actors use to deploy unauthorized tasks in Amazon Elastic Container Service (Amazon ECS), including abuse of overly permissive task execution roles. Role Assumption and Federated Access has been expanded to cover new cross-account role assumption variations and identity provider manipulation, with sharper guidance for distinguishing legitimate federated access from unauthorized use.

The current trend

This June update reflects a clear trend: threat actors are increasingly targeting container orchestration platforms and using organizational trust relationships to their advantage. The container techniques show that as organizations adopt Kubernetes at scale, the attack surface grows with it. The organization-level techniques show that threat actors understand organizational trust relationships.

The common thread is that every one of these techniques operates within the boundaries of legitimate functionality. Modifying a workload, assuming cross-account trust, and joining an organization are all expected actions in healthy environments.. Detection, then, depends entirely on context: the principal, the timing, and the sequence of events that follows.

The Threat Technique Catalog for AWS is designed to help with this. We encourage teams to review the relevant entries and assess whether their current monitoring would catch these patterns:

  • Unexpected modifications to EKS workload specifications
  • Pod deployments that use unsigned container images
  • sts:AssumeRoot calls into member accounts
  • Unbounded compute consumption in your EKS clusters that could be prevented by resource quotas
  • Unexpected organization invitations to your accounts

Each of the threats leaves traces in AWS CloudTrail and Kubernetes audit logs, and the TTC provides specific guidance on what to watch for and how to respond.

Looking ahead

The Threat Technique Catalog for AWS exists because we believe the patterns we observe during security engagements shouldn’t stay behind closed doors. When we see techniques repeating across customers, the most effective thing we can do is document them and make that knowledge available so you can act on it before you’re in the middle of an incident.

This June update adds five new entries and updates three existing ones, and the catalog will continue to evolve. Our team updates it based on what we’re seeing in the real world when helping customers respond to security events. We encourage security teams to review the catalog, incorporate its techniques into threat modeling exercises, and use it as a shared vocabulary for discussing cloud-specific threats.

Explore the full catalog: Threat Technique Catalog for AWS – Full Matrix

Additional resources

If you have feedback about this post, submit comments in the Comments section below.


Shannon Brazil

Shannon Brazil is a Sr. security engineer, managing a team on the AWS Customer Incident Response Team (CIRT), specializing in digital forensics and cloud security investigations. Known in the community as 4n6lady, she is passionate about security education and mentoring the next generation of defenders.

Cydney Stude

Cydney Stude

Cydney is a security engineer specializing in threat intelligence and incident response at AWS. Cydney works on the ground in incident response and is passionate about turning observables into security outcomes. Cydney is an author and maintainer of the Threat Technique Catalog for AWS.

Javier Teitelbaum

Javier Teitelbaum

Javier is security engineer on the AWS Customer Incident Response Team (CIRT), with a focus in building and threat intelligence.

Restrict AWS Management Console access to expected networks with sign-in resource-based policies and RCPs

Post Syndicated from Swara Gandhi original https://aws.amazon.com/blogs/security/restrict-aws-management-console-access-to-expected-networks-with-sign-in-resource-based-policies-and-rcps/

Amazon Web Services (AWS) recently announced support for resource-based policies and resource control policies (RCPs) for AWS Sign-In. By using resource-based policies and RCPs, you can restrict access to the AWS Management Console sign-in and aws login CLI sessions to requests from your expected networks, your on-premises data center networks, and your Amazon Virtual Private Cloud (Amazon VPC) VPCs.

Sign-in resource-based policies and RCPs support several security objectives: restricting console sign-in to corporate networks, limiting which principals can sign-in to the console, and applying consistent network perimeter controls across an entire AWS Organizations organization.

In this post, we walk through a common use case: a financial services company restricting console access to its corporate network for regulatory compliance. We show you how to implement this using a sign-in resource-based policy for a single account, verify the controls with AWS CloudTrail, and explain how these policies integrate with AWS Management Console Private Access and the broader AWS data perimeter framework.

Restricting console sign-in access to a corporate network

Consider a financial services company that requires access to AWS Management Console sign-in to originate from the corporate network. The company has the following requirements:

  • Users sign in to the console only from the corporate VPN, office network, or customer VPC.
  • Sign-in attempts from personal networks, public Wi-Fi, or other unexpected locations must be denied.
  • A designated principal should retain access from any network to prevent lockout.
  • All sign-in attempts (allowed and denied) must be logged to CloudTrail for compliance evidence.

In the steps that follow, we show you how to create a resource-based policy to enforce these requirements on a single account.

Prerequisites

  • AWS Command Line Interface (AWS CLI) installed and configured with the latest version.
  • Permission to manage Sign-in resource policies. Attach the AWS managed policy AWSSignInResourcePolicyManagement or grant permissions to the following actions to respective principals:
    • Manage resource permission statements: signin:PutResourcePermissionStatement, signin:DeleteResourcePermissionStatement, signin:ListResourcePermissionStatements, signin:GetResourcePolicy.
    • Manage console authorization: signin:PutConsoleAuthorizationConfiguration, signin:GetConsoleAuthorizationConfiguration, signin:DeleteConsoleAuthorizationConfiguration
  • Identified corporate network: IP CIDR range or VPC ID.
  • Designated principal Amazon Resource Name (ARN) to exclude, so it retains access if network conditions change.

Note: For the complete list of AWS Sign-In actions see Actions, resources, and condition keys for AWS Sign-In in the Service Authorization Reference.

Step 1: Create resource permission statements

Most resource-based policies require the author to input the full policy document (JSON statements). A Sign-in resource permission statement is different: you provide parameters, and AWS Sign-In generates the policy for you.

The following command provides your corporate IP range, your VPC, and an excluded principal as parameters. AWS Sign-In uses these parameters to generate a policy that restricts console sign-in to those networks, while letting the excluded principal sign in from any network. You control the parameter values, not the policy structure. You can review the generated policy at any time with the get-resource-policy command.

Note: Creating resource permission statements has no effect until console authorization is enabled in Step 2, so you can review the complete policy before it takes effect. Write operations must target us-east-1.

To create resource permission statements

1. Open your terminal and ensure you have the latest AWS CLI installed.
2. Run the following command, replacing the placeholder values <my-vpc>, <my-vpc-region>, <my-corporate-cidr>, and <excluded-IAM-principal-arn> with your specific configuration:

aws signin put-resource-permission-statement \
  --source-vpc <my-vpc> \
  --requested-region <my-vpc-region> \
  --source-ip <my-corporate-cidr> \
  --excluded-principal <excluded-IAM-principal-arn> \
  --region us-east-1

3. Verify the command succeeded by checking for a statementId in the output.

Example output:
{
“statementId":"b2HfHli9qCF1P4eGNll13CrZtusXlcPxxVBqz2aYLjlAcWtWQHP6Hg0"
}

4. Review the complete resource-based policy by running get-resource-policy command.

aws signin get-resource-policy

Example output:

{
  "signinResourceBasedPolicy": {
    "Version": "2012-10-17",
    "Statement": [
      {
        "Effect": "DENY",
        "Principal": {"AWS": "*"},
        "Action": ["signin:Authenticate"],
        "Resource": "*",
        "Condition": {
          "ArnNotEquals": {"signin:PrincipalArn": ["<excluded-IAM-principal-arn>"]},
          "NotIpAddress": {"aws:SourceIp": ["<my-corporate-cidr>"]},
          "StringEquals": {"aws:ResourceAccount": ["<account-id>"]},
          "StringNotEquals": {"aws:SourceVpc": ["<my-vpc>"]}
        }
      },
      {
        "Effect": "DENY",
        "Principal": {"AWS": "*"},
        "Action": ["signin:CreateOAuth2Token", "signin:AuthorizeOAuth2Access"],
        "Resource": "*",
        "Condition": {
          "ArnNotEquals": {"aws:PrincipalArn": ["<excluded-IAM-principal-arn>"]},
          "NotIpAddress": {"aws:SourceIp": ["<my-corporate-cidr>"]},
          "StringEquals": {"aws:ResourceAccount": ["<account-id>"]},
          "StringNotEquals": {"aws:SourceVpc": ["<my-vpc>"]}
        }
      },
      {
        "Effect": "DENY",
        "Principal": {"AWS": "*"},
        "Action": ["signin:Authenticate"],
        "Resource": "*",
        "Condition": {
          "ArnNotEquals": {"signin:PrincipalArn": ["<excluded-IAM-principal-arn>"]},
          "StringEquals": {"aws:SourceVpc": ["<my-vpc>"]},
          "StringNotEquals": {"aws:RequestedRegion": ["<my-vpc-region>"]}
        }
      },
      {
        "Effect": "DENY",
        "Principal": {"AWS": "*"},
        "Action": ["signin:CreateOAuth2Token", "signin:AuthorizeOAuth2Access"],
        "Resource": "*",
        "Condition": {
          "ArnNotEquals": {"aws:PrincipalArn": ["<excluded-IAM-principal-arn>"]},
          "StringEquals": {"aws:SourceVpc": ["<my-vpc>"]},
          "StringNotEquals": {"aws:RequestedRegion": ["<my-vpc-region>"]}
        }
      }
    ]
  }
}

The generated policy contains four statements, grouped into two pairs. The first pair restricts access by network source—it denies any principal making a request from outside your corporate IP range (<my-corporate-cidr>) or your VPC (<my-vpc>). The second pair restricts which AWS Region your VPC can target—it denies requests originating from <my-vpc> unless they are directed at <my-vpc-region>. This Region binding is necessary because VPC IDs are only unique within a single Region.

AWS Sign-In evaluates these policies in two phases: before authentication and after authentication. The post-authentication evaluation repeats each time the console session requests new credentials. Within each pair, one statement covers the pre-authentication phase and one covers the post-authentication phase.

The pre-authentication statement evaluates the signin:Authenticate action. Since the principal is not yet authenticated in this phase, the statement uses the signin:PrincipalArn condition key to exempt your excluded principal. This key supports all principal types: root user, AWS Identity and Access Management (IAM) user, federated user, and role.

The post-authentication statement evaluates the signin:AuthorizeOAuth2Access and signin:CreateOAuth2Token actions. AWS Sign-In evaluates these actions after authentication, when it issues the tokens that establish the console session. These actions do not support the signin:PrincipalArn key. Instead, they use aws:PrincipalArn, which resolves to the authenticated principal.

The aws:ResourceAccount value is the recipient account ID. AWS Sign-In pulls it automatically from your caller credentials, so you do not set it yourself. For the full list of supported actions and condition keys, including which keys apply at each phase and to each principal type, see Controlling console access with resource-based policies and resource control policies and AWS Sign-In condition keys reference.

Step 2: Turn on sign-in policy enforcement for your account

This step turns on enforcement of the policy you created in Step 1. Until you run this step, the resource permission statements you created in Step 1 have no effect.

5. Turn on enforcement of sign-in policies using the following command:

aws signin put-console-authorization-configuration \
  --target-id <account-id> \
  --region us-east-1

6. Verify the command succeeded by checking for a “consoleAuthorizationEnabled": true in the output.

Example output:

{
“Output": {
“consoleAuthorizationEnabled": true,
“scope": “ACCOUNT”,
“targetId": "<account-id>"
}
}

7. You can also verify the configuration by executing the get-console-authorization-configuration command as shown below:

aws signin get-console-authorization-configuration \
  --target-id <account-id> \
  --region us-east-1

8. To disable enforcement or remove individual statements, use delete-console-authorization-configuration or delete-resource-permission-statement. For more details, see Controlling console access with resource-based policies and resource control policies in the AWS Sign-In User Guide.

Verifying the implementation

Now that enforcement is active, sign-in attempts are evaluated against your resource-based policy. Verify the behavior by testing sign-in from different network conditions.

Scenario 1: Allowed sign-in from the corporate network

A principal signing in from the allowed corporate IP range or VPC succeeds normally. The CloudTrail event shows ConsoleLogin:Success

Example CloudTrail event details for successful console sign-in:

{
    "userIdentity": {
        "type": "AssumedRole",
        "principalId": "AROAEXAMPLEID:Dev1",
        "arn": "arn:aws:sts::123456789123:assumed-role/Developer/Dev1",
        "accountId": "123456789123"
    },
    "eventTime": "2026-06-09T19:20:38Z",
    "eventSource": "signin.amazonaws.com",
    "eventName": "ConsoleLogin",
    "awsRegion": "us-east-1",
    "sourceIPAddress": "192.0.2.100",
    "responseElements": {
        "ConsoleLogin": "Success"
    },
    "eventID": "dd004e78-6447-4f56-8d2d-a795da66f598",
    "readOnly": false,
    "eventType": "AwsConsoleSignIn",
    "managementEvent": true,
    "recipientAccountId": "123456789123",
    "eventCategory": "Management"
}

Scenario 2: Denied sign-in from an unexpected network

A principal signing in from a network other than the allowed IP address range or a VPC endpoint attached to the source VPC, is blocked. The CloudTrail event shows ConsoleLogin: Failure with an error message identifying the policy that caused the denial:

Example CloudTrail event details for failed console sign-in:

{    
"userIdentity": {
    "type": "IAMUser",
    "accountId": "123456789123",
    "accessKeyId": "",
    "userName": "Dev1"
    },
    "eventTime": "2026-06-09T19:20:38Z",
    "eventSource": "signin.amazonaws.com",
    "eventName": "ConsoleLogin",
    "awsRegion": "us-east-1",
    "sourceIPAddress": "198.51.100.76",
    "userAgent": "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/148.0.0.0 Safari/537.36",
    "errorCode": "AccessDenied",
    "errorMessage": "Authorization denied because of a resource-based policy",
    "requestParameters": null,
    "responseElements": {
        "ConsoleLogin": "Failure"
    },
"eventID": "d88a7543-ae89-4186-b1b6-d3116413f2ee",
"readOnly": false,
"eventType": "AwsConsoleSignIn",
"managementEvent": true,
"recipientAccountId": "123456789123",
"eventCategory": "Management"
}

The error message field shows the policy type that caused the denial: “Authorization denied because of a resource-based policy”.

Scaling with RCPs

The steps above apply a Sign-in resource-based policy to a single account. For organizations managing many accounts, RCPs offer a better path: they can be attached at the organization, OU, or account level in AWS Organizations and apply automatically to every account in scope. To view an RCP example, see here .

When a sign-in to the console is denied because of an RCP, the error message field shows the denial as “Authorization denied because of a resource control policy”.

Extending with Console Private Access and data perimeters

The sign-in resource-based policy you created controls which networks can reach your account’s sign-in flow. AWS Management Console Private Access adds a complementary control: from within your network, it limits console access to a known set of AWS accounts, preventing sign-in to unexpected AWS accounts.

Together, these capabilities contribute to a data perimeter for console access:

  • Network perimeter: Sign-in resource-based policies and RCPs restrict console sign-in to expected networks (corporate IP ranges, VPCs).
  • Identity perimeter: Sign-in resource-based policy and RCP ensure only trusted identities can sign in to the console. Console VPC endpoint policy and Sign-in VPC endpoint policy ensure only trusted identities can use the console from your VPC.
  • Resource perimeter: Sign-in VPC endpoint policy and Console VPC endpoint policy restrict which AWS accounts are reachable from your network.

The controls in this post focus on console access. To extend these perimeters to other AWS services and broader implementation scenarios, see the Data perimeter policy examples repository and the Data Perimeters Blog Post Series.

Conclusion

By using sign-in resource-based policies and RCPs, you can restrict AWS Management Console access to expected networks. These controls are available at no additional cost in all AWS commercial Regions.

To get started, see the AWS Sign-in User Guide. For organization-wide enforcement, see Resource control policies in the AWS Organizations User Guide.

If you have feedback about this post, submit comments in the Comments section below.


Swara Gandhi

Swara Gandhi is a Senior Solutions Architect on the AWS Identity Solutions team. She works on building secure and scalable end-to-end identity solutions. She is passionate about everything identity, security, and cloud.

Rishi Tripathy

Rishi Tripathy

Rishi is a Principal Product Manager on the AWS Identity and Access Management (IAM) team. He focuses on access control mechanisms that help enterprises secure their AWS environments at scale. He is passionate about building security primitives that are straightforward to adopt and hard to misconfigure.

Prevent data exfiltration: AWS egress controls for cloud workloads

Post Syndicated from Meriem SMACHE original https://aws.amazon.com/blogs/security/prevent-data-exfiltration-aws-egress-controls-for-cloud-workloads/

When securing an Amazon Web Services (AWS) environment, teams naturally prioritize inbound controls, firewalls, WAFs, and access policies, because that’s where the most visible threats originate. Outbound traffic, on the other hand, tends to get less attention. It’s often left open by default to avoid breaking application dependencies and because the risk feels less immediate. But overlooking egress means missing a key layer of defense. Without visibility into what’s leaving your network, it’s harder to detect unintended data flows, whether from misconfigured services, overly broad permissions, or workloads with unauthorized access.

Real-world incidents highlight why egress controls deserve attention across both traditional cloud workloads and emerging AI-driven architectures.

In traditional cloud environments, application-level security issues remain a persistent threat. For example, when CVE-2025-55182 (React2Shell) was publicly disclosed in December 2025, multiple organized groups began exploitation attempts within hours, targeting unpatched React Server Components to achieve remote code execution. After a workload is accessed by an unauthorized party, they typically establish outbound command-and-control channels and begin exfiltrating data. Without egress controls in place, that outbound traffic can flow freely, and the unauthorized access might go unnoticed until a compliance audit, customer complaint, or incident notification forces discovery.

Agentic AI systems introduce a new dimension to this risk. The OWASP Top 10 for Agentic Applications identifies threats such as Agent Goal Hijack (ASI01), where unauthorized parties manipulate an autonomous agent’s objectives to silently exfiltrate data, and Unexpected Code Execution (ASI05), where an agent with unauthorized access generates and runs potentially damaging code that establishes reverse shells or transfers sensitive data to external endpoints. As organizations deploy AI agents with access to tools, APIs, and code interpreters, these agents become high-value targets, and their outbound network activity must be constrained with the same rigor as any other workload.

In both scenarios, the common thread is unauthorized outbound traffic. In this post, we show you how to implement layered egress detection and protection using AWS services working together to reduce unauthorized data transfer risk, whether the source is an application with unauthorized access or a manipulated AI agent.

Architecture overview

Figure 1: Hub-and-spoke egress control architecture

Figure 1: Hub-and-spoke egress control architecture

The following architecture, shown in Figure 1, illustrates one approach to implementing a hub-and-spoke network pattern for a multi-account AWS environment. Note that alternative designs might be appropriate depending on your organizational requirements and constraints.

Application workloads reside in spoke virtual private clouds (VPCs) that connect to an AWS Transit Gateway, which serves as the central hub for routing inter-VPC and internet-bound traffic while enforcing network segmentation through carefully crafted route tables. Spoke VPCs use VPC endpoints for secure AWS service access, keeping traffic within the AWS network where possible. VPC endpoint policies are applied as key data perimeter controls, restricting which principals can access AWS services and which resources can be accessed through these endpoints.

Internet-bound traffic is routed through a transit gateway-attached AWS Network Firewall, which inspects and filters outbound flows before they reach the internet. This centralized routing model scales horizontally by adding spoke VPCs without modifying the inspection infrastructure, making it well suited for organizations that have multiple AWS accounts.

It’s important to understand that Amazon Route 53 Resolver DNS Firewall must be deployed across your VPCs to filter DNS queries that resolve through the Route 53 VPC Resolver. (DNS queries sent directly to other DNS resolvers bypass it, but can be filtered with AWS Network Firewall.) The DNS firewall uses both managed and custom domain lists to filter DNS queries, blocking resolution of known unauthorized domains before any network connection is established.

Data perimeter controls are enforced at multiple layers: service control policies (SCPs) and resource control policies (RCPs) at the AWS Organizations level, VPC endpoint policies at the network level, and resource policies on individual services. AWS IAM Access Analyzer is deployed at the organization level to continuously detect publicly accessible or externally shared resources.

A detection layer comprising Amazon GuardDuty, AWS Security Hub, and IAM Access Analyzer provides continuous monitoring and threat detection. Findings are routed through an integration layer using Amazon EventBridge, which triggers AWS Lambda-based automated remediation and sends notifications using Amazon Simple Notification Service (Amazon SNS). This integration layer also feeds back into your network controls, automatically updating Network Firewall deny rules and DNS Firewall block lists based on detected threats.

Centralized observability is achieved through Amazon CloudWatch Logs and CloudWatch dashboards. Network Firewall flow logs and alert logs are collected centrally to support incident investigation and compliance reporting.

This architecture applies equally to traditional application workloads and AI-driven workloads. An AI agent running on Amazon Bedrock, for example, typically sits inside a spoke VPC. When that agent invokes an external API or attempts to reach the internet, its traffic follows the same path through Transit Gateway and Network Firewall as any Amazon Elastic Compute Cloud (Amazon EC2) or container workload. The agent doesn’t get a special lane out, it’s subject to the same domain allow-lists, the same DNS filtering, and the same data perimeter policies.

That said, agents often need outbound access to invoke external tools or third-party APIs as part of their normal operation, which makes allow-list design more nuanced. You will want to scope allowing domains tightly to the specific endpoints your agents legitimately need, rather than opening broad categories. Complementing these network-layer controls with application-layer guardrails such as Amazon Bedrock Guardrails—which can filter harmful content and detect prompt attacks before they reach the network layer—adds another layer of defense.

Preventive controls

The following preventive controls block data exfiltration before it occurs. Because they actively disrupt traffic, reserve them for activity that is confirmed or highly likely to be potentially damaging.

AWS Network Firewall

Consider this scenario: an unauthorized party compromises an EC2 instance in one of your spoke VPCs and attempts to exfiltrate sensitive data to an external server. Now consider an agentic AI scenario: an unauthorized party uses prompt injection to hijack an AI agent’s goal (OWASP ASI01), redirecting it to exfiltrate training data to an external endpoint. Network Firewall is designed to block this attempt because the unauthorized destination isn’t on the approved domain allow-list—the same control that stops an EC2 instance with unauthorized access— also stops a manipulated AI agent.

Without centralized egress inspection, that traffic flows directly to the internet through a NAT gateway. Network Firewall prevents this by providing centralized, Layers 3–7 deep packet inspection with advanced threat intelligence capabilities, including IP address, port, and protocol filtering; plus packet content inspection using Suricata-compatible rules.

In this architecture, Transit Gateway funnels internet-bound traffic from multiple spoke VPCs through Network Firewall for centralized inspection. The firewall endpoint becomes the target for 0.0.0.0/0 routes, routing outbound internet traffic for inspection before reaching NAT gateways for address translation. In both scenarios, Network Firewall blocks the exfiltration attempt at the network layer before data leaves your environment. Its key capabilities include:

  • Domain name filtering: Block traffic to unauthorized destinations (such as a command-and-control server at *.untrusted-domain.com)
  • IP and port rules: Define explicit allow-lists for external IPs your applications truly need, blocking everything else
  • Domain category filtering: Block entire categories of domains that your workloads should never communicate with
  • IDS and IPS: Detect and block known attack patterns in outbound traffic using Suricata-compatible rules
  • Port and protocol enforcement: Help ensure only expected protocols use their designated ports (for example, only HTTPS on TCP port 443), preventing protocol tunneling
  • Geographic IP filtering: Block outbound traffic to geographic regions where your organization has no business relationships
  • TLS decryption: Inspect encrypted traffic to detect exfiltration attempts hidden within HTTPS connections
  • Threat intelligence integration: Use managed threat intelligence (such as active threat defense that uses the Amazon threat intelligence system MadPot) feeds or custom Suricata rules to detect unexpected patterns
  • Automatic scaling: Handles up to 100 Gbps per Availability Zone

For multi-account environments, AWS Firewall Manager can centrally deploy and manage Network Firewall across your organization’s accounts, helping maintain consistent egress rules everywhere. Additionally, AWS Network Firewall Proxy (in preview) offers explicit proxy capabilities with granular HTTP/HTTPS filtering—including URL path and HTTP method-level controls—for workloads that require application-layer inspection of outbound web traffic.

Route 53 Resolver DNS Firewall

DNS queries made through Route 53 VPC Resolver don’t pass through the outbound network path inspected by Network Firewall or third-party firewalls. Unauthorized parties can take advantage of this by encoding sensitive data within DNS queries to external servers, a technique known as DNS tunneling. This risk extends to agentic AI workloads. An agent with code execution capabilities (OWASP ASI05) could be tricked into running a script that encodes sensitive data (like customer records, model weights, API keys) into DNS queries directed at an externally controlled nameserver. DNS Firewall is designed to block these queries regardless of whether they originate from a traditional workload or an AI agent, because the filtering happens at the resolver level before any connection is established.

Because DNS traffic is essential for normal operations and often overlooked in security architectures, it represents a common unauthorized data exfiltration channel. Route 53 Resolver DNS Firewall closes this gap by filtering and potentially blocking outbound DNS queries from your VPCs. Its core capabilities consist of:

  • Block unauthorized domains: AWS provides managed domain lists, including an Aggregate Threat List covering malware, ransomware, botnet, spyware, and DNS tunneling
  • Enforce allow-lists: Permit only queries to approved domains, blocking everything else
  • DNS Firewall Advanced features: AI and machine learning (AI/ML)-backed detection of DNS tunneling, Domain Generation Algorithms (DGAs), and dictionary DGAs

Configuration is straightforward: Create rule groups with domain match lists and actions (block, allow, and alert), then associate them with your VPCs. The DNS resolver applies these rules to every DNS query made from instances in the VPC through Route 53 Resolver. This prevents unauthorized parties from using DNS tunneling to exfiltrate data, a technique that completely bypasses inspection by firewalls in the egress VPC.

For a deeper look at the risks associated with DNS exfiltration and DNS Firewall Advanced capabilities, see Protect against advanced DNS threats with Amazon Route 53 Resolver DNS Firewall.

Data perimeters

A data perimeter is a set of preventive guardrails that allow only your trusted identities to access trusted resources from expected networks. While the preceding controls secure the network paths out of your environment, data perimeters secure the API-level paths, helping to ensure that even if an unauthorized party gains access to valid credentials, they can’t use AWS service APIs to move data to resources outside your organization.

This comprehensive approach uses three primary AWS capabilities working together:

  1. Service control policies (SCPs): Organization-wide preventive controls that restrict what identities can do. In the context of egress protection, SCPs can prevent users from creating resources that bypass your egress controls (for example, preventing the creation of VPCs without DNS Firewall associations or blocking the use of services that could establish alternative outbound paths).
  2. Resource control policies (RCPs): Controls that restrict API access to your resources. While RCPs aren’t directly egress controls, they act as a complementary layer. For example, they can block attempts to access your Amazon Simple Storage Service (Amazon S3) buckets from outside your organization at the resource level.
  3. VPC endpoint policies: VPC endpoints enable private communication with AWS services without traffic going through the internet. VPC endpoint policies are resource-based AWS Identity and Access Management (IAM) policies that govern what can be accessed through that endpoint. This is where data perimeters most directly function as an egress control.

Consider the following VPC endpoint policy that restricts Amazon S3 access through the endpoint to only S3 buckets within your organization, directly preventing an insider or a workload with unauthorized access from copying data to an external S3 bucket:

{
  "Statement": [{
    "Sid": "DenyAccessToNonOrgBuckets",
    "Effect": "Deny",
    "Principal": "*",
    "Action": "s3:*",
    "Resource": "*",
    "Condition": {
      "StringNotEqualsIfExists": {
        "aws:ResourceOrgID": "<my-org-id>"
      }
    }
  }]
}

This policy is designed to deny any Amazon S3 operation through this VPC endpoint unless the target S3 bucket belongs to your organization. Without this control, a workload with unauthorized access could use aws s3 cp to copy sensitive data to an externally controlled bucket in a different AWS account.

Data perimeter policies don’t grant new permissions, they narrow what’s accessible by establishing guardrails, acting as a second authorization layer. By implementing these perimeters using IAM condition keys like aws:PrincipalOrgID, aws:ResourceOrgID, aws:SourceVpc, and aws:SourceVpce, you create layered permissions guardrails that help prevent unintended access patterns and configuration errors.

For more information on implementing perimeter controls, explore the Building a Data Perimeter AWS whitepaper.

Detective controls

The following detective controls surface data exfiltration attempts after they occur. Because they observe rather than disrupt traffic, you can apply them broadly to flag unexpected activity for investigation. Use the findings to identify recurring unauthorized patterns that can graduate into preventive controls.

Amazon GuardDuty: Detective control for egress threats

GuardDuty serves as your critical detection layer for egress protection, continuously monitoring for outbound threats that evade or take advantage of your preventive controls. GuardDuty identifies behavioral anomalies and attack patterns that indicate active data exfiltration attempts. Its egress-focused detection capabilities include:

  • DNS-based data exfiltration detection: The Trojan:EC2/DNSDataExfiltration finding alerts when EC2 instances are transferring data through DNS channels. GuardDuty also identifies queries to DGA domains commonly used for command-and-control communication.
  • Known malicious actor detection: Exfiltration:S3/MaliciousIPCaller triggers when Amazon S3 data APIs like GetObject or CopyObject are invoked from IP addresses on AWS threat intelligence feeds, signaling active data extraction attempts.
  • Multi-step attack sequence correlation: GuardDuty Extended Threat Detection correlates multiple unexpected events to identify multi-stage exfiltration campaigns. For example, AttackSequence: S3/CompromisedData detects when unauthorized parties modify S3 bucket policies to broaden access and then systematically extract data using stolen credentials.

GuardDuty findings serve dual purposes in your egress strategy. Alerts about attempted exfiltration that failed confirm your preventive layers (Network Firewall, DNS Firewall, and data perimeters) are functioning effectively: the threat was detected because it progressed far enough to trigger behavioral analysis, but your controls blocked the actual data loss. Conversely, findings indicating successful exfiltration trigger immediate incident response workflows, enabling you to contain active incidents, revoke stolen credentials, and quarantine affected resources before significant damage occurs.

Integrate GuardDuty with Security Hub for centralized correlation across your security services and implement automated response through EventBridge and Lambda functions to enable real-time containment when high-severity exfiltration findings occur.

IAM Access Analyzer

IAM Access Analyzer helps identify potential data exfiltration paths by detecting resources accessible from outside your AWS account or organization. It uses automated reasoning technology to analyze resource-based policies and identify which of your resources can be accessed by external entities (principals outside your zone of trust), continuously monitoring public and cross-account access.

External access analyzers identify resources shared with external principals (such as other AWS accounts or public access). For example, when an S3 bucket is configured to allow access outside your zone of trust through bucket policies, ACLs, or access points, IAM Access Analyzer generates a finding with details about the access path, including the external principal and the level of access granted. Security teams can respond by taking immediate action to remove unintended access or by setting up automated notifications through EventBridge to engage development teams for remediation.

AWS Security Hub

Security Hub exposure findings provide a comprehensive view of potential security risks by correlating data from multiple AWS security services. These findings identify when resources might be vulnerable to data exfiltration by integrating intelligence from GuardDuty (for threat detection), Amazon Inspector (for vulnerability assessment), Security Hub CSPM (for configuration compliance), and Amazon Macie (for sensitive data discovery). For example, it can identify when a publicly exposed S3 bucket contains sensitive data and isn’t encrypted at rest, flagging it as a potential data exfiltration risk that requires immediate attention.

AWS Shield network security director (in preview) complements Security Hub by discovering and analyzing your network topology to identify resources with unrestricted outbound internet access, helping you detect potential egress blind spots across your environment.

Egress security strategy

You don’t need to implement all these controls at once. The following phased approach lets you build your egress security posture incrementally, at a pace that matches your organization’s operational maturity and risk tolerance.

  • Phase 1 – Quick wins: Enable Route 53 DNS Firewall across your VPCs to close the DNS exfiltration gap. Enable GuardDuty across your accounts for baseline threat detection.
  • Phase 2 – Foundational: Deploy organization-wide data perimeters (SCPs, RCPs, and VPC endpoint policies). Deploy Network Firewall as a transit gateway-attached firewall.
  • Phase 3 – Efficient: Enable IAM Access Analyzer for continuous external access detection. Implement automated remediation through EventBridge and Lambda to update firewall rules in real time. Centralize findings in Security Hub with automated alerting.

Conclusion

Egress security isn’t a single control—it’s a layered strategy. Start by assessing your current posture across network filtering, DNS security, data perimeters, and detective controls. Identify the gaps, then follow the phased approach outlined in this post to close them incrementally. Regular testing through simulated exfiltration attempts validates that your controls work effectively. These controls apply with equal force to agentic AI workloads, where manipulated agents can become unintended exfiltration vectors. Put egress under control and turn your outbound blind spots into monitored checkpoints.

If you have feedback about this post, submit comments in the Comments section below.


Merriem-SMACHE

Meriem SMACHE

Meriem is a Security Specialist Solutions Architect at AWS, supporting customers in the design and deployment of resilient cloud and AI solutions, from generative AI workloads to fully autonomous agentic systems, that meet their regulatory requirements and security needs.

Maxim Raya

Maxim Raya

Maxim is a Security Specialist Solutions Architect at AWS. In this role, he helps clients accelerate their cloud transformation by increasing their confidence in the security and compliance of their AWS environments.

Accelerate security investigations with Kiro CLI

Post Syndicated from Sibasankar Behera original https://aws.amazon.com/blogs/security/accelerate-security-investigations-with-kiro-cli/

When a security event occurs in your Amazon Web Services (AWS) environment, rapid response is critical. However security teams often struggle with time-consuming, manual processes that slow down investigations. Analysts must recall complex AWS Command Line Interface (AWS CLI) syntax for multiple services, manually correlate findings across Amazon GuardDuty, AWS CloudTrail, and other security tools, and document every investigation step for compliance requirements. They make critical decisions under pressure while active threats continue. For analysts without deep AWS expertise, these challenges are even more pronounced, creating bottlenecks in your security operations.

Kiro is an AI-powered coding assistant that helps users write, understand, and optimize code through integrated development environment (IDE) and command line integrations. Beyond traditional development tasks, it offers AWS-specific expertise including architecture guidance, best practices, cost optimization recommendations, and service documentation navigation. Kiro CLI puts Kiro’s full capabilities in your terminal, making it a natural fit for security operations workflows. For example, with built-in tools, Kiro CLI can be used to help with investigation of a GuardDuty finding—it will propose the appropriate AWS CLI commands, explain what each command does, and wait for your approval before executing. This approach lets you focus on analyzing threats rather than figuring out how to investigate them.

This blog post demonstrates how to use Kiro CLI to conduct a security investigation following the AWS Security Incident Response Guide framework. This framework organizes incident response into five phases:

  1. Preparation: Having the right tools and processes in place before an incident occurs
  2. Detection and analysis: Identifying security events and understanding their scope
  3. Containment: Limiting the impact of an incident and preventing further damage
  4. Eradication and recovery: Removing threats and restoring normal operations
  5. Post-incident activity: Learning from incidents to improve future response

You’ll see how you can use Kiro CLI to triage GuardDuty findings, assess impacted Amazon Elastic Compute Cloud (Amazon EC2) resources, analyze AWS CloudTrail logs, and generate remediation scripts. By the end of this post, you’ll learn how to use Kiro CLI to run security investigations in minutes rather than hours — without skipping steps.

Prerequisites

Before getting started, confirm you have the following:

  • Install Kiro CLI (available for macOS, Linux and Windows)
  • Kiro access, either:
    • Create a free AWS Builder ID account
    • Use your organization’s Kiro Pro subscription
  • AWS CLI: Configure using one of the methods in Configuring settings for the AWS CLI. Kiro CLI uses the default AWS CLI profile (or the profile specified by the AWS_PROFILE environment variable) to interact with AWS resources and will request your approval before executing any actions.

Solution overview

To show Kiro CLI in action, we investigate a GuardDuty finding end to end — following the AWS Security Incident Response Guide framework through the following steps.

  1. Discovery: Retrieve and analyze a high-severity GuardDuty finding
  2. Resource analysis: Examine EC2 instance configuration, security groups, and AWS Identity and Access Management (IAM) permissions
  3. Containment: Isolate the compromised instance and revoke excessive permissions
  4. Evidence preservation: Create forensic snapshots using Amazon Elastic Block Store (Amazon EBS) snapshots
  5. Scope assessment: Analyze CloudTrail logs to determine event scope
  6. Proactive defense: Establish automated alerting using Amazon Simple Notification Service (Amazon SNS) and Amazon EventBridge
  7. Knowledge capture: Create reusable investigation workflows through steering files

Throughout this investigation, Kiro CLI will propose commands, explain their purpose, wait for approval, and automatically document findings—transforming an inefficient manual process into a guided, efficient workflow.

Kiro CLI combines AI reasoning with deep AWS knowledge to analyze security findings, correlate evidence across services, and propose appropriate AWS CLI commands at each step of an investigation. While this AI-powered approach accelerates investigations, it’s important to validate outputs and recommendations before taking action. The specific commands and analysis shown in this walkthrough are examples—your results will vary based on your specific findings and environment configuration.

The investigation: From alert to resolution

In this section, we walk you through the phases of an investigation, from discovery through analysis.

Discovery: A high-severity GuardDuty finding

Our investigation began with a GuardDuty finding requiring immediate attention. Rather than manually constructing AWS CLI commands, we used Kiro CLI’s natural language interface:

I need to investigate GuardDuty finding 58cddb4e8705cde3f595ef5805f50491 in us-east-1. Please help me understand this finding by checking the finding details, resource details, and threat details. For each investigation step, propose the AWS CLI command, explain what information we'll get, and wait for my confirmation before showing the next command. Document everything in a findings.md file in the current directory, including finding summary, investigation steps, evidence collected, and remediation guidance. Structure it for both technical and executive audiences.

This single prompt establishes the entire investigation framework, as shown in Figure 1. By requesting step-by-step approval, we maintain control while benefiting from AI guidance. The documentation requirement helps ensure that we’re building an audit trail in real-time for compliance requirements.

Figure 1: Kiro CLI interface showing the initial investigation prompt and proposed first command to retrieve GuardDuty detector ID and finding details

Figure 1: Kiro CLI interface showing the initial investigation prompt and proposed first command to retrieve GuardDuty detector ID and finding details

Kiro CLI proposed retrieving the detector ID and complete finding details. After approval, it executed the commands and revealed critical information, as shown in Figure 2.Key findings:

  • Type: CryptoCurrency:EC2/BitcoinTool.B!DNS
  • Severity: HIGH (8.0)
  • Instance: i-05447e6dacd0a7e7e (m5.xlarge)
  • Threat: 617 DNS queries to pool.minergate.com
  • Timeline: Started 9 minutes after instance launch

We can see that it took 9 minutes from instance launch to mining activity, which suggests automated event rather than manual action. This timeline information, automatically extracted and highlighted by Kiro CLI, helps security teams understand event patterns.

Figure 2: GuardDuty finding details showing HIGH severity cryptocurrency mining detection with threat indicators and timeline

Figure 2: GuardDuty finding details showing HIGH severity cryptocurrency mining detection with threat indicators and timeline

Resource and scope analysis

Kiro CLI proposed investigating the EC2 instance configuration, security groups, IAM permissions, and checking for additional findings. This proactive suggestion demonstrates Kiro CLI’s understanding of security investigation workflows, it knows that understanding the potential impact requires examining not just what the unauthorized user did, but what might possibly be a next step in a typical threat scenario.

The following information is also shown in Figure 3.

Instance configuration: Kiro CLI retrieved the instance details, revealing:

  • Amazon Linux 2023 AMI
  • Instance Metadata Service version 2 (IMDSv2) required (good security posture)
  • Public IP address with unrestricted outbound access
  • IAM instance profile attached

Security group assessment: Kiro CLI analyzed the security group rules and identified:

  • No inbound rules
  • Unrestricted outbound access to 0.0.0.0/0, enabling mining traffic

IAM permission analysis: Kiro CLI examined the instance profile and attached role policies, uncovering a critical security risk:

  • Critical finding: AdministratorAccess policy attached to the EC2 instance profile
  • Full AWS account access from compromised instance
  • Potential for complete account takeover

While the observed activity is cryptocurrency mining, the attached AdministratorAccess policy means the unauthorized user could have exfiltrated data, created backdoors, or compromised other resources. This highlights why least-privilege IAM policies are critical. Even if an instance is compromised, limited permissions help reduce the potential impact.

Figure 3: Kiro CLI’s instance configuration summary highlighting the AdministratorAccess policy, unrestricted outbound access, and multiple concurrent security findings

Figure 3: Kiro CLI’s instance configuration summary highlighting the AdministratorAccess policy, unrestricted outbound access, and multiple concurrent security findings

Scope assessment: Kiro CLI checked for additional unexpected activity and discovered seven security findings on this single instance, indicating a multi-vector attack, as shown in Figure 4.

Figure 4: Kiro CLI’s summary highlighting a multi-vector attack.

Figure 4: Kiro CLI’s summary highlighting a multi-vector attack.

Containment actions

Kiro CLI proposed a systematic remediation plan aligned with the knowledge obtained by following AWS Security Incident Response Guide’s containment strategy, as shown in Figure 5.

Figure 5: Kiro CLI’s summary of the investigation and recommendations for immediate actions.

Figure 5: Kiro CLI’s summary of the investigation and recommendations for immediate actions.

Instance isolation: Kiro CLI produced commands to create an isolation security group with no inbound or outbound rules (as shown in Figure 6), then applied it to the compromised instance. This containment step stops new connections without destroying evidence. However, it’s important to understand that security groups are stateful and use connection tracking. When you change security group rules, existing connections aren’t immediately interrupted and continue to allow packets until they time out.

This means that if an unauthorized user has an active connection to the instance, that connection might persist temporarily even after applying the isolation security group. For immediate interruption of all traffic including active connections, consider also implementing network access control lists (NACLs), which are stateless and don’t track connection state. Unlike security groups, NACLs can immediately break existing connections when rules are applied. While NACLs operate at the subnet level (broader scope than instance-level security groups), they provide an additional layer of defense that helps ensure network isolation.

This scenario illustrates an important principle: while AI-powered tools such as Kiro CLI can help you respond more quickly by generating appropriate commands, it’s critical to keep a human in the loop who understands these nuances. Kiro CLI might not have complete information about edge cases, so security professionals should validate recommendations and consider additional controls based on their expertise and the specific threat scenario.

Figure 6: Instance successfully isolated with confirmation showing no inbound or outbound rules, blocking all network traffic including command-and-control (C&C) communications and mining activity

Figure 6: Instance successfully isolated with confirmation showing no inbound or outbound rules, blocking all network traffic including command-and-control (C&C) communications and mining activity

Privilege revocation: Kiro CLI generated commands to attach a deny-all policy to the compromised IAM role (as shown in Figure 7). The AI assistant explained that even though the AdministratorAccess policy remains attached, the deny-all policy takes precedence because of the evaluation logic used by IAM, where explicit denies always override any allows. This immediately revoked all permissions while preserving the original configuration for forensic analysis.

Figure 7: IAM credentials revocation confirmation with current status checklist showing network isolated, IAM credentials revoked, and forensic snapshot pending

Figure 7: IAM credentials revocation confirmation with current status checklist showing network isolated, IAM credentials revoked, and forensic snapshot pending

Evidence preservation

Before making mutating changes, Kiro CLI recommended creating a forensic snapshot of the compromised instance’s Amazon EBS volume (as shown in figure 8). This step can be missed when teams are under pressure to contain an active threat, but it’s critical for post-incident analysis and potential legal proceedings.

Memory preservation decision: We chose to leave the instance running in its isolated state rather than stopping it immediately. Stopping an EC2 instance results in loss of volatile memory containing forensic evidence such as running processes, network connections, loaded malware, and encryption keys. By maintaining the instance in an isolated security group with all network access blocked, we neutralized the threat while preserving the ability to conduct deeper forensic investigation if needed.

Volatile memory often contains evidence that explains how an event occurred, malware binaries, decryption keys, or command-and-control (C&C) communications that disappear when an instance stops. This decision point illustrates the balance between immediate threat elimination and thorough investigation.

Capturing volatile memory requires specialized tools and techniques. For Linux instances, LiME (Linux Memory Extractor) can capture physical memory, while Windows instances can use tools like Winpmem. After being captured, memory dumps can be analyzed using Volatility, an open source memory forensics framework. Forensics tools should be pre-installed on your systems to avoid changes being made during the evidence gathering process. AWS provides guidance on automating forensic kernel module builds for Amazon Linux EC2 instances to streamline this process.

Figure 8: Forensic snapshot creation confirmation with proper tagging including purpose, incident ID, and severity for evidence preservation

Figure 8: Forensic snapshot creation confirmation with proper tagging including purpose, incident ID, and severity for evidence preservation

CloudTrail analysis

To understand the full scope of compromise, we asked Kiro CLI to analyze CloudTrail logs. The AI assistant identified available CloudTrail trails and proposed queries to find any API calls made from the compromised instance using its temporary credentials (as shown in Figure 9).

CloudTrail analysis is often the most time-consuming part of incident investigation, requiring analysts to construct complex queries and correlate events across time. Kiro CLI automates this process, immediately identifying the relevant log sources and proposing appropriate queries.

Figure 9: Kiro CLI identifying available CloudTrail trails and proposing targeted queries

Figure 9: Kiro CLI identifying available CloudTrail trails and proposing targeted queries

Kiro CLI found no unexpected API calls originating from the instance credentials—no IAM users created, no S3 buckets accessed, and no secrets stolen. The event appeared limited to cryptocurrency mining activity conducted through DNS queries, with no evidence of data exfiltration or lateral movement.

Figure 10: Investigation results from Kiro CLI

Figure 10: Investigation results from Kiro CLI

This shows the value of thorough CloudTrail analysis: even when initial findings suggest a contained threat, confirming the absence of broader compromise is essential before closing an investigation.

Building proactive defenses

The AWS Security Incident Response Guide emphasizes that preparation is the foundation of effective incident response. With the immediate threat contained, we used Kiro CLI to strengthen our preparation phase by establishing automated alerting for future incidents.

As shown in Figure 11, we used natural language to request

Set up a notification system that sends an email to [email] for any high severity or higher severity findings.

Kiro CLI understood the requirement and proposed a multi-step solution involving Amazon SNS and EventBridge:

  1. Create an SNS topic for GuardDuty alerts
  2. Subscribe an email address to the topic
  3. Create an EventBridge rule to trigger on high-severity findings (severity greater than or equal to 7.0)
  4. Configure the SNS topic as the EventBridge target
  5. Grant EventBridge permissions to publish to the SNS topic

Building automated alerting requires understanding multiple AWS services, their interactions, and correct configuration syntax. Kiro CLI translates a straightforward natural language request into a complete, production-ready solution.

Auto-correction and testing: When setting up complex integrations, commands can fail because of permission issues, incorrect Amazon Resource Name (ARN) references, or malformed JSON policies. Kiro CLI automatically detects these failures and proposes corrected commands.

Figure 11: Notification system setup completion showing SNS topic created, EventBridge rule configured, and confirmation that notifications will trigger on HIGH and CRITICAL severity findings

Figure 11: Notification system setup completion showing SNS topic created, EventBridge rule configured, and confirmation that notifications will trigger on HIGH and CRITICAL severity findings

You can also prompt Kiro CLI to test the setup: Test this notification system to verify it’s working correctly. Kiro CLI will verify that the SNS subscription is confirmed, check that the EventBridge rule is properly configured, validate IAM permissions, identify any misconfigurations, and publish a test event to verify end-to-end functionality. This intelligent error handling means security teams can confidently deploy automation without manual troubleshooting.

Creating reusable investigation workflows

With the immediate threat contained and proactive defenses in place, we then used Kiro CLI to create a reusable steering file that codifies this investigation workflow for future incidents. Steering files are Markdown files stored in .kiro/steering/ that act as persistent memory for Kiro CLI, helping security teams capture institutional knowledge and standardize response procedures. To share them across your team, add them to a Git repository or publish them to your documentation system like Confluence — the same places you’d keep any other runbook.

We recommend running the full investigation and generating the steering file in the same Kiro CLI session. This way, the steering file captures the exact steps, commands, and decisions from your investigation. Navigate the process the way that fits your organization — the steering file will reflect your workflow, not a generic template.

We asked Kiro CLI:

Create a steering file that captures this GuardDuty investigation workflow so future analysts can follow the same systematic approach.

Kiro CLI generated a detailed steering file at .kiro/steering/guardduty-incident-response.md that includes:

  • Investigation phases aligned with the AWS Security Incident Response Guide
  • AWS CLI command patterns for GuardDuty, Amazon EC2, IAM, and CloudTrail
  • Documentation requirements and approval gates
  • Containment, eradication, and evidence preservation procedures

This is the example steering file that was created by Kiro cli:

--- 
inclusion: manual 
--- 
 
# GuardDuty Incident Response Workflow 
 
This steering file guides systematic investigation of GuardDuty findings following AWS Security Incident Response Guide best practices. 
 
## Investigation Phases 
 
### Detection and Analysis 
1. Retrieve GuardDuty finding details using finding ID 
2. Extract finding type, severity, affected resources, and threat indicators 
3. Document timeline of events (instance launch, threat detection) 
 
### Resource Analysis 
4. Investigate EC2 instance configuration (AMI, IMDS version, network access) 
5. Analyze security group rules (inbound/outbound access) 
6. Review IAM permissions attached to instance profile 
7. Check for additional findings on the same resource 
 
### Containment 
8. Create isolation security group with no inbound/outbound rules 
9. Apply isolation security group to compromised instance 
10. Create forensic snapshot before making destructive changes 
11. Preserve volatile memory by keeping instance running if forensic analysis needed 
 
### Eradication 
12. Revoke excessive IAM permissions 
13. Document all actions in findings.md with technical and executive summaries 
 
### Analysis 
14. Query CloudTrail for API calls from compromised instance credentials 
15. Assess scope of compromise and potential lateral movement 
 
## Documentation Requirements 
- Finding summary with severity and type 
- Investigation steps with timestamps 
- Evidence collected (security groups, IAM policies, CloudTrail logs) 
- Remediation actions taken 
- Recommendations for prevention 
 
## AWS CLI Command Patterns 
- GuardDuty: `aws guardduty get-findings` 
- EC2: `aws ec2 describe-instances`, `aws ec2 describe-security-groups` 
- IAM: `aws iam get-instance-profile`, `aws iam list-attached-role-policies` 
- CloudTrail: `aws cloudtrail lookup-events` 
 
## Approval Gates 
Always propose commands with explanations before execution and wait for approval. 

Traditional incident response playbooks are static documents that quickly become outdated. Kiro CLI steering files are executable playbooks that guide AI-assisted investigations with consistency while remaining flexible enough to adapt to specific scenarios. Steering files stay current because updating them is part of the workflow, not a separate task. When you adjust your investigation process, ask Kiro CLI to update the steering file at the end of the session. It captures your changes, and you share the updated version with the team through Git or Confluence — everyone works from the latest version.

Conclusion

Security incidents require accurate and rapid response, but traditional investigation workflows create bottlenecks that extend mean time to respond (MTTR). By following the framework provided by the AWS Security Incident Response Guide and using Kiro CLI’s AI-powered capabilities, you can transform incident response from reactive to proactive, well-documented operations.

In this post, we demonstrated how Kiro CLI accelerates each phase of the incident response lifecycle—from initial detection and analysis through containment, eradication, and recovery. You learned how to use natural language prompts to investigate GuardDuty findings, analyze compromised resources, implement containment measures, preserve forensic evidence, and establish automated alerting for future incidents. The steering file capability helps your team embed hard-won expertise in reusable workflows that benefit analysts at all skill levels.

Whether you’re investigating alerts, building defenses, or documenting procedures, Kiro CLI provides the expertise and automation to respond faster, learn continuously, build better defenses, and document thoroughly. When commands fail or configurations are wrong, Kiro CLI identifies the issue and corrects it, reducing time spent troubleshooting.

If you have feedback about this post, submit comments in the Comments section below.


Sibasankar Behera

Sibasankar Behera

Sibasankar is a Senior Solutions Architect at AWS in the Automotive and Manufacturing team. He is passionate about AI, data and security. In his free time, he loves spending time with his family and reading non-fiction books.

Author

Marshall Jones

Marshall is a Worldwide Security Specialist Solutions Architect at AWS. His background is in AWS consulting and security architecture and focused on a variety of security domains including edge, threat detection, and compliance. Today, he’s focused on helping enterprise AWS customers adopt and operationalize AWS security services to increase security effectiveness and reduce risk.

Spring 2026 SOC 1 and 2 reports are now available in OSCAL format

Post Syndicated from Thomas Fischer original https://aws.amazon.com/blogs/security/spring-2026-soc-1-and-2-reports-are-now-available-in-oscal-format/

Amazon Web Services (AWS) is excited to release the Spring 2026 System and Organization Controls (SOC) 1 and 2 reports in machine-readable OSCAL format alongside the PDF version of the reports. The reports cover 188 services over the 12-month period from April 1, 2025 to March 31, 2026, giving customers a full year of assurance. These reports demonstrate our continuous commitment to adhering to the heightened expectations of cloud service providers.

AWS is the first major cloud provider to offer key compliance reports to customers in the National Institute of Standards and Technology’s (NIST) Open Security Controls Assessment Language (OSCAL), as of June 2026. OSCAL is an open source, machine-readable (JSON) format for security information. The SOC 1 and SOC 2 report package in OSCAL format is now available as a distinct package in AWS Artifact, marking a milestone toward open, standards-based compliance automation. This machine-readable version of the SOC report package enables workflow automation to reduce manual processing time and modernize security and compliance processes. Your use cases for this content are innovative, and we want to hear about them through the contact information found in the OSCAL report package.

You can download the Spring 2026 SOC 1 and 2 reports in OSCAL format through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact. The SOC 3 report can be found on the AWS SOC Compliance page and in AWS Artifact.

AWS strives to continuously bring services into the scope of its compliance programs to help customers meet their architectural and regulatory needs. You can view the current list of services in scope on our Services in Scope page. As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback about SOC compliance.

To learn more about AWS compliance and security programs, see AWS Compliance Programs.

If you have feedback about this post, submit comments in the Comments section below.

Thomas Fischer

Thomas Fischer

Thomas is a Principal at AWS, focused on scaling product delivery and applications to transform security, risk, and compliance. He has over 20 years of experience in enterprise IT transformation and worked for different consulting companies managing large teams and programs across multiple regulated industries and sectors. Thomas holds CISSP, CCSP, CGEIT, and PMP certifications.

Tushar-Jain

Tushar Jain

Tushar is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Tushar holds a Master of Business Administration from Indian Institute of Management Shillong, India and a Bachelor of Technology in electronics and telecommunication engineering from Marathwada University, India. He has over 14 years of experience in information security and holds CISM, CCSK and CSXF certifications.

Fritz Kunstler

Fritz is a Principal Security Engineer at AWS, currently focused on AI applications to transform security governance, risk, and compliance. Fritz has been an AWS customer since 2008 and an Amazonian since 2016.

Baj Bajwa

Baj Bajwa

Baj is a Security Assurance Manager at AWS, where he leads the Global Third-Party Assurance product portfolio within the Compliance and Security Assurance (CSA) organization. He has over 15 years of experience in information security, compliance, and risk management, and holds a master’s degree in cybersecurity. Baj maintains CISSP, CISA, PMP, CCSK, GISF, and ICAgile certifications.

Introducing AWS Continuum: Security at machine speed

Post Syndicated from Chet Kapoor original https://aws.amazon.com/blogs/security/introducing-aws-continuum-security-at-machine-speed/

What we believe

We’ve been thinking deeply about enterprise security. The operating model that served us for the past decade (collect telemetry, store it, query it, build dashboards to watch it) is no longer keeping pace. We need to shift to the new world: telemetry, context, reasoning, and actions. An approach that produces outcomes. The latest cybersecurity frontier models further made this shift urgent. Models like Claude Mythos can now find software vulnerabilities and reason through complex attack paths at machine-speed, leading to an exponentially increasing backlog of vulnerabilities.

Introducing AWS Continuum for code vulnerabilities

Today, we’re announcing AWS Continuum for code vulnerabilities, now available in gated preview. Continuum for code vulnerabilities addresses the full lifecycle of a code vulnerability at machine speed: from discovery through actions. It reasons over your environment, confirms what is real, and drives toward resolution. It’s model agnostic, using multiple frontier models where each performs best, and is built to incorporate the latest and most capable models as they emerge.

Continuum is built on lessons learned from running security across AWS and Amazon.com. Securing businesses that operate in different industries required a system that understands business context rather than applying generic rules uniformly.

How it works

Continuum for code vulnerabilities reasons over your full environment. This context includes structured data already living in Amazon Web Service (AWS) (your infrastructure, permissions, network topology, code) and the unstructured data that captures how your organization operates and your risk profile (your documents, communications, business priorities).

Continuum for code vulnerabilities operates in four continuous phases.

  1. Discovery: Security teams tackle a backlog of vulnerabilities, and many are already using frontier models to find more. Continuum starts by ingesting that existing backlog and performing its own vulnerability scan of your environment. This creates a more comprehensive view of vulnerabilities and the associated attack paths.
  2. Prioritization: Continuum uses context to evaluate, enrich, and prioritize every finding. Is the affected component deployed, is it reachable, is it in a production path, and what would the business impact be if exploited? The result is an evidence-backed list of priorities, allowing Continuum and your team to focus on what’s most important.
  3. Validation: Continuum validates findings to surface false positives before they waste your team’s time. It contextualizes vulnerabilities against your environment. It then constructs working exploit examples in a sandboxed environment that provide concrete, reproducible evidence of the issue.
  4. Mitigation and remediation: Continuum assesses existing defenses around a validated issue, including blocking and compensating controls along with detection mechanisms. It then draws on its understanding of the codebase, context, and findings to recommend mitigation or remediation of the vulnerability with a network change, policy change, or code patch. The patch recommendation is validated using the same system that confirmed the vulnerability. It also provides blast radius visibility and rollback paths where feasible.

This is just the beginning. We’re starting with code (1st and 3rd party) and then expanding to other aspects of security.

Trust is graduated

Continuum starts in learn mode with a human in the loop. Every recommendation includes the reasoning behind it. As you gain confidence, you can graduate Continuum to enforce mode, enabling remediation that can be increasingly automated based on categories and risk profiles you define.

Continuum capabilities

In addition to Continuum for code vulnerabilities, Continuum includes capabilities you might already know. The AWS Security Agent penetration testing and code scanning functionality is now part of Continuum as Continuum pen testing and Continuum code scanning (Preview). We’re also launching Continuum threat modeling in preview, which automatically generates comprehensive threat models from design documents or source code and outputs results in STRIDE format. These capabilities serve as detection and analysis sources that feed into the broader Continuum loop of discovery, prioritization, validation, and remediation.

Getting started

We’re working with customers across financial services, automotive, and technology to shape AWS Continuum. Customer feedback confirms the direction: security teams want tools that earn trust and take action.

AWS Continuum for code vulnerabilities is available in gated preview. Sign up to request access at AWS Continuum.

If you have feedback about this post, submit comments in the Comments section below.


Chet Kapoor

Chet Kapoor

Chet is Vice President of Search, Security, and Observability at Amazon Web Services. With more than two decades in enterprise technology, he has led companies through some of the industry’s most consequential platform shifts — from APIs and open source to cloud and AI — building and scaling businesses through periods of rapid growth, transformation, acquisition, and IPO. He brings a builder’s mindset, deep operational experience, and a strong customer orientation to helping organizations adopt emerging technologies securely and at scale.

Threat tactic spotlight: Subdomain takeover

Post Syndicated from Matt Gurr original https://aws.amazon.com/blogs/security/threat-tactic-spotlight-subdomain-takeover/

In this blog post you’ll learn how to detect and prevent subdomain takeover – a tactic where threat actors exploit dangling DNS records to redirect traffic to attacker-controlled resources. We’ll explain the issue, how the situation arises, and how you can use various AWS features and services to help mitigate the impact of this tactic.

Under the shared responsibility model, securing configurations in the cloud is your responsibility. AWS supports you through strong defaults, guidance in the Security Pillar of the Well-Architected Framework, and security services to help you meet that responsibility. The AWS Customer Incident Response Team (AWS CIRT) also monitors for new and trending tactics that threat actors use to exploit specific customer configurations, so that you can make informed design decisions and improve your response plans.

AWS CIRT has observed threat actors actively scanning for public DNS CNAME records that point to resources that no longer exist, looking for subdomain takeover opportunities.

Note: The subdomain takeover tactic does not leverage vulnerabilities of AWS services. It exploits a dangling DNS record to redirect traffic to an attacker-controlled resource.

Quick DNS Primer

CNAME Records: A CNAME (Canonical Name) record is a DNS entry that points one domain name to another. For example, api.example.com can be configured to point to api.example.s3-website-us-east-1.amazonaws.com. This feature of DNS enables users to configure a memorable, human-friendly domain name while the actual resource lives at a longer, machine-generated AWS hostname. A security issue emerges when the target resource is deleted but the CNAME record pointing to it remains – creating a “dangling” record.

Dangling Records: When a resource (like an S3 bucket) is deleted but the DNS record pointing to it is left behind, that DNS record becomes “dangling”, pointing to a resource that no longer exists. For resources in globally shared namespaces, threat actors can potentially reclaim the name of your deleted resource and serve malicious content through your DNS record.

What is subdomain takeover?

A subdomain is a prefix added to a domain that allows you to organize access to your resources. A subdomain takeover occurs when you delete the underlying resource and a threat actor creates a new resource with the same name to take advantage of the DNS records still pointing to it.

A subdomain takeover is possible when a CNAME record points to an AWS resource that uses a globally shared DNS namespace where the resource name can be chosen by any AWS customer. The following AWS resources meet these criteria:

Amazon S3 (global namespace): Bucket names like mybucket.s3.amazonaws.com are globally unique and can be claimed by any account if the bucket is deleted. Note: S3 buckets created with account regional namespaces (launched March 2026) are scoped to your account and are not subject to this issue.

Amazon CloudFront: Distribution domain names like d111111abcdef8.cloudfront.net are assigned by AWS and cannot be chosen by an attacker. However, if you delete a distribution and another customer creates one that happens to receive the same domain name, a dangling CNAME could resolve to their content.

AWS Elastic Beanstalk: Environment names like myapp.elasticbeanstalk.com are globally unique and can be claimed by any account if the environment is terminated.

Resources like Amazon VPC, Amazon EC2 instances, or private hosted zones are not subject to this tactic because they do not expose globally claimable DNS namespaces.

MITRE ATT&CK classifies this technique under T1584.001: Compromise Infrastructure – Domains.

Analyzing an example scenario

Consider the following scenario:

You create a DNS CNAME record pointing to your S3 website endpoint. The subdomain subdomain.example.com now resolves to subdomain.example.s3-website-us-east-1.amazonaws.com, which serves content from the S3 bucket named subdomain.example. If your team deletes the bucket and forgets to delete the DNS record, users that navigate to the site will see an error stating that the bucket doesn’t exist. However, at this point, if a threat actor sees this error and moves in to claim the bucket name, they will be able to set up their own site that users will see when they navigate to the subdomain.example.com site.

Figure 1 shows an S3 bucket named subdomain.example (a globally unique bucket name) configured to host a static website, with the S3 website endpoint subdomain.example.s3-website-us-east-1.amazonaws.com.

Figure 1: S3 bucket configured as a static website

Figure 1: S3 bucket configured as a static website

As shown in Figure 2, we use Amazon Route 53 to create a CNAME record to resolve to our Amazon domain name; to give users a friendly name and so they do not have to remember the long S3 website name in URLs.

Figure 2: DNS Resolver configured with CNAME record pointing to origin bucket

Figure 2: DNS Resolver configured with CNAME record pointing to origin bucket

The customer’s AWS administrator decides to stop serving content from the S3 bucket and deletes it, as shown in Figure 3.

Figure 3: Resource deleted without removing the CNAME record

Figure 3: Resource deleted without removing the CNAME record

With the S3 bucket deleted and the CNAME record still in place, the DNS record is now dangling. A threat actor identifies this situation and creates a new S3 bucket with the same global name subdomain.example in an AWS account that the threat actor controls, as shown in Figure 4. The threat actor can now serve content from this new bucket, including potentially malicious content. End users remain unaware of this switch and continue to access subdomain.example.com, trusting the content because it appears to originate from a URL they recognize.

Figure 4: Subdomain takeover happens

Figure 4: Subdomain takeover happens

Potential impacts of a sub-domain takeover

Consider these potential impacts:

Reputation risk: There is a potential risk to your organization’s reputation, because you don’t control the content being served from the threat actor’s site that your DNS record points to.

Potential exposure to phishing campaigns: Users within your organization might have the subdomain bookmarked in their browser, not knowing the resource is no longer available, then unsuspectingly navigate to the site that now hosts malware or is used to phish user credentials.

Blocking: If the subdomain is flagged by security vendors for malicious activity, it could impact your business operations.

Financial loss: Subdomain takeover incidents can result in a financial impact due to the potential disruption to service delivery as you deal with the event.

Proactive detection

AWS Config for proactive detection

For proactive detection, you can use AWS Config to continuously monitor your Route 53 CNAME records and verify that the target resources exist in your account.

Prerequisite: This approach requires AWS Config recorder to be enabled for the resource types you want to monitor (S3 buckets, CloudFront distributions, Elastic Beanstalk environments). If Config isn’t recording a resource type, it won’t appear in the inventory check. For more information, see Setting up AWS Config with the console.

Why use AWS Config inventory instead of DNS resolution checks?

A common approach is to check whether a CNAME resolves to a valid endpoint. However, this method has a critical flaw: if an attacker has already claimed the resource, DNS resolution will succeed – to their resource, not yours. You would have no indication that you don’t own what’s responding.

By querying AWS Config’s recorded configuration items, you’re checking whether the resource exists in your account inventory, not just whether something responds at that DNS name. This approach correctly identifies dangling CNAMEs even after a takeover has occurred.

Implementation approach:

Account-level vs. organization-level scope

The reference implementation queries AWS Config inventory within a single account. This means that if a CNAME record in Account A points to a resource that legitimately exists in Account B within the same AWS organization, the rule will flag it as NON_COMPLIANT.

For organizations that share resources across accounts, you can modify the solution to use an AWS Config Aggregator, which queries resource inventory across all accounts in your organization. This is similar to how IAM Access Analyzer supports both account-level and organization-level scopes. To use this approach, you need an organization-level Config Aggregator already configured, and the Lambda function’s IAM role needs the config:SelectAggregateResourceConfig permission.

We recommend starting with account-level scope for simplicity, then expanding to organization-level if your environment includes cross-account resource sharing.

The main idea is to create a custom AWS Config rule that queries your Route 53 hosted zones for CNAME records, then parses each CNAME target to determine whether it points to a known AWS resource pattern such as S3, CloudFront, or Elastic Beanstalk. For each match, the rule cross-references the target against your AWS Config inventory to verify that the resource actually exists in your account. If the resource isn’t found, the rule marks the CNAME record as NON_COMPLIANT, surfacing it for review.

The Config rule should focus on known AWS resource patterns:

  • S3: *.s3.amazonaws.com, *.s3-website-<region>.amazonaws.com
  • CloudFront: *.cloudfront.net
  • Elastic Beanstalk: *.elasticbeanstalk.com

Note: CNAME records pointing to external third-party services are outside the scope of this detection mechanism, as those resources won’t appear in your AWS Config inventory.

NON_COMPLIANT findings from your Config rule can be routed to AWS Security Hub for centralized visibility, or trigger SNS notifications to alert your security team.

Figure 5: Dangling DNS Detection Solution

Figure 5: Dangling DNS Detection Solution

Reference implementation:

We’ve published a complete implementation of this detection approach as an open-source solution. The solution deploys a Lambda function that discovers CNAME records across all your Route 53 hosted zones and uses pattern matching to identify targets pointing to S3, CloudFront, and Elastic Beanstalk. It then queries your AWS Config inventory to verify whether each target resource still exists in your account. When a dangling record is detected, the solution generates a HIGH severity finding in Security Hub and can optionally send SNS notifications to alert your security team. A CloudWatch metrics dashboard is also included for ongoing compliance tracking.

Deployment:

# Clone the repository
git clone https://github.com/aws-samples/sample-dangling-dns-detection
cd sample-dangling-dns-detection

# Build the Lambda deployment package
./scripts/package.sh

# Upload to S3
aws s3 cp dist/dangling-dns-detection.zip s3://YOUR_BUCKET/

# Deploy the CloudFormation stack
aws cloudformation deploy \
  --template-file infrastructure/template.yaml \
  --stack-name dangling-dns-detection \
  --parameter-overrides \
      LambdaCodeS3Bucket=YOUR_BUCKET \
      EvaluationFrequency=TwentyFour_Hours \
  --capabilities CAPABILITY_NAMED_IAM

The stack creates an AWS Config custom rule that runs on your specified schedule (default: every 24 hours), evaluating all CNAME records and reporting compliance status.

Mitigating the effects

Mitigating subdomain takeover requires both preventive procedures and responsive capabilities.

Prevention: Standard operating procedure

The most effective mitigation is a standard operating procedure for resource deprovisioning that ensures DNS records are removed before the underlying resource:

  1. Within your DNS zone, delete the CNAME record that points to the fully qualified domain name (FQDN) of the resource that you plan to deprovision.
  2. Wait for the DNS TTL to expire before deleting the resource. DNS resolvers cache records for the duration of the TTL (for example, a TTL of 3600 means resolvers may serve the old record for up to one hour). If you delete the resource before the TTL expires, a threat actor could claim the resource name while cached CNAME entries are still directing traffic to it.
  3. Deprovision the resource that you no longer want to use.
  4. Run a DNS check of the CNAME record that you removed to verify that the resource is no longer resolving.

Key principle: Always delete DNS first, wait for the TTL to expire, then delete the resource. This order eliminates the window where a dangling record could be exploited.

Prevention: S3 account regional namespaces

As mentioned earlier, AWS introduced account regional namespaces for Amazon S3 general purpose buckets in March 2026. While this is a meaningful step toward mitigating the S3-specific takeover vector, there are important operational limitations to be aware of:

Existing buckets are unaffected. Buckets already created in the global namespace cannot be migrated to an account regional namespace. The bucket names remain globally unique and claimable by anyone if the bucket is deleted.

Global namespace is still the default. When creating a new bucket through the console, CLI, or SDK, the global namespace remains the default selection. Users who aren’t aware of the new option will continue creating globally-scoped buckets.

Existing IaC templates require updates. Existing infrastructure-as-code templates (CloudFormation, CDK, Terraform) that don’t explicitly opt in to the account regional namespace will continue provisioning buckets in the global namespace. For CloudFormation, this means setting the BucketNamespace property to account-regional. For other IaC tools, consult their documentation for the equivalent configuration. Organizations need to audit and update their templates to opt in.

For these reasons, the dangling DNS detection approach described in this post remains critical – particularly for organizations with existing S3 infrastructure, and for CloudFront, and Elastic Beanstalk resources where no equivalent namespace scoping exists.

Response: Notification and remediation

When a dangling DNS record is detected, the reference solution described in the Detection section automatically creates a HIGH severity finding in AWS Security Hub and reports the CNAME record as NON_COMPLIANT in AWS Config. If you provide an SNS topic ARN during deployment, the solution also sends notifications to alert your security or operations team via email, Slack, or other channels. For production environments, consider a human-in-the-loop workflow where these notifications are reviewed by a team member who approves the DNS record deletion before it’s executed. This prevents accidental deletion of legitimate records during transient issues.

The reference solution also includes a CloudWatch dashboard for tracking compliance status and evaluation metrics over time, giving your team ongoing visibility into DNS health across your hosted zones.

Note: Fully automated remediation (auto-deleting DNS records) carries risk – a false positive could disrupt legitimate services. We recommend starting with detection and notification, then evaluating automation based on your detection accuracy and operational maturity.

Conclusion

Subdomain takeover is a preventable misconfiguration that can have significant impact on your organization. A layered defense approach provides the best protection:

Prevention: Implement a standard operating procedure that deletes DNS records before deprovisioning the underlying resource.

Detection: Use AWS Config custom rules to proactively identify CNAME records pointing to resources that no longer exist in your account.

Response: Configure notifications through SNS or Security Hub so your team can respond quickly when dangling records are detected.

Monitoring: Maintain ongoing visibility through CloudWatch dashboards to track DNS health and compliance status.

The key insight is that good DNS hygiene – knowing when your CNAME records point to a nonexistent resource – is your first line of defense. Automated detection through AWS Config provides a safety net when operational procedures fail. And if you detect an issue, having a playbook ready to enact your response can lower the impact and your mean time to recovery.

If you have feedback about this post, submit comments in the Comments section below.


Matt Gurr

Matthew Gurr

Matthew is the Senior Incident Response lead in the Asia-Pacific region for the AWS Customer Incident Response Team (AWS CIRT). He has a passion for helping customers proactively prepare for a security event. In his spare time, he enjoys cycling, music, and reading.

Luis Pastor

Luis Pastor

Luis is a Senior Security Solutions Architect at AWS leading the Infrastructure Security and Compliance Technical Field Communities. He drives security architecture for enterprise customers across financial services, healthcare, and retail, specializing in cloud security transformation and regulatory compliance frameworks. Before AWS, Luis architected security solutions in hybrid cloud environments.

Geoff Sweet

Geoff Sweet

Geoff has been in industry since the late 1990s. He began his career in electrical engineering. Starting in IT during the dot-com boom, he has held a variety of diverse roles, such as systems architect, network architect, and, for the past several years, security architect. Geoff specializes in infrastructure security.

Ariam Michael

Ariam Michael

Ariam is a Solutions Architect at AWS. She has supported various customers in the Worldwide Public Sector, specifically SLG and Federal Civilian customers. She is passionate about security, specifically Data Protection helping customers implement encryption and best practices.

ICYMI: May 2026 @AWS Security

Post Syndicated from Rodolfo Brenes original https://aws.amazon.com/blogs/security/icymi-may-2026-aws-security/

Read all about the latest AWS security features, compliance updates, and hands-on resources in our new, monthly digest posts. You’ll find expert blog posts, new service capabilities, code samples, and workshops.

AWS Security Blog posts

This month’s AWS Security Blog posts covered AI security, network protection, identity management, compliance frameworks, and supply chain security. Read on for practical guidance on securing agentic AI workflows, filtering network traffic by category, defending against supply chain attacks, and more.

AI Security

Security posture improvement in the AI era
Author: Celeste Bishop | Published: May 1, 2026
Learn to use the Security Health Improvement Program (SHIP) to strengthen security fundamentals across 10 core use cases for confident AI adoption.

Enabling AI sovereignty on AWS
Author: Stéphane Israël | Published: May 12, 2026
Learn how AWS delivers control and choice across the AI stack to help customers meet digital and AI sovereignty requirements.

The AWS AI Security Framework: Securing AI with the right controls, at the right layers, at the right phases
Authors: Riggs Goodman III, Christopher Rae | May 15, 2026
A structured framework that helps security leaders align the right security controls to the right AI use case, at the right layer, at the right deployment phase.

Why Policy in Amazon Bedrock AgentCore chose Cedar for securing agentic workflows
Authors: Liana Hadarean, Jean-Baptiste Tristan | May 20, 2026
Learn how Cedar’s deterministic authorization, automated reasoning, and formal verification capabilities secure agentic AI tool invocations through Amazon Bedrock AgentCore Gateway.

Infrastructure security

Securing open proxies in your AWS environment
Author: Dodd Mitchell | Published: May 4, 2026
Learn to identify and secure open proxies in your AWS environment to prevent abuse, protect your IP reputation, and control costs.

Introducing AI traffic analysis dashboards for AWS WAF
Authors: Christopher Jen, Eitav Arditti, Kaustubh Phatak | Published: May 5, 2026
A new dashboard providing visibility into AI bot and agent activity including bot identification, intent classification, and access pattern analysis.

Simplifying policy management with URL and Domain Category filtering on AWS Network Firewall
Authors: Lawton Pittenger, Sofía Aluma-Santos, Eric Fortenbery, Mostafa Elkhouly | May 28, 2026
Learn to use AWS Network Firewall’s URL and domain category filtering to control access to website categories like AI services, manage exceptions for approved domains, and monitor traffic patterns with Amazon CloudWatch Logs Insights.

    Why and how to migrate to a Transit Gateway-attached AWS Network Firewall


    Authors: Frank Phillis, Lawton Pittenger | May 28, 2026

    Learn to migrate your centralized AWS Network Firewall deployment to a
    AWS Transit Gateway-attached model, eliminating the inspection
    Amazon VPC and enabling flexible cost allocation.

    Identity

    Regional routing for AWS access portals: Implementing custom vanity domains for IAM Identity Center
    Authors: Georgi Baghdasaryan, Laura Reith, Sowjanya Rajavaram | May 14, 2026
    Learn to build a custom vanity domain with latency-based routing and automated failover for IAM Identity Center multi-Region access portals.

    Automating identity lifecycle and security with AWS Directory Service APIs
    Authors: Ali Alzand, Kevin Sookhan | May 21, 2026
    Learn to use the new AWS Directory Service Data APIs with Amazon GuardDuty and AWS Step Functions to automate identity lifecycle management and respond to security threats.

    Governance and compliance

    Announcing the ISO 31000:2018 Risk Management on AWS compliance guide
    Authors: Jesse McMahan, Akanksha Chaturvedi, Mayur Jadhav, Juan Rodriguez, Sana Rahman | Published: May 1, 2026
    A compliance guide providing practical guidance for establishing a risk management program using ISO 31000:2018 principles in AWS environments.

    New compliance guide available: ISO/IEC 42001:2023 on AWS
    Authors: Abdul Javid, Amber Welch, Muhammad Sharief, Jonathan Jenkyn, Satish Uppalapati | Published: May 6, 2026
    A compliance guide providing practical guidance for designing and operating an Artificial Intelligence Management System (AIMS) using AWS services.

    Introducing the updated AWS User Guide to Governance, Risk, and Compliance for Responsible AI Adoption
    Authors: Krish De, Stephen James Martin, Brenda Fong, Kelvin Leung | May 13, 2026
    An updated guide providing FSI customers practical considerations for responsible AI adoption across governance, risk management, compliance, data management, and AI agent management.

    Governing infrastructure as code using pattern-based policy as code
    Authors: Guptaji Teegela, Paul Keastead | May 19, 2026
    Learn to use Open Policy Agent (OPA) in CI/CD pipelines to validate AWS infrastructure changes before deployment using recurring control patterns.

    Import historical data from AWS CloudTrail Lake to Amazon CloudWatch
    Authors: Isaiah Salinas, Erik Weber|Published: May 6, 2026
    Learn to import historical data from AWS CloudTrail Lake into Amazon CloudWatch for centralized log analysis.

    Data protection

    Automating post-quantum cryptography readiness using AWS Config
    Author: Pravin Nair | May 14, 2026
    Learn to use the PQC Readiness Scanner to inventory your ALB, NLB, and Amazon API Gateway endpoints and continuously monitor their TLS configurations for post-quantum cryptography readiness.

    Threat detection and response

    Detecting and preventing crypto mining in your AWS environment
    Authors: Jason Palmer, Nadia Mahmood | May 13, 2026
    Learn to use Amazon GuardDuty to identify and mitigate cryptocurrency mining threats in your AWS environment with a multi-layered defense strategy.

    Well-architected best practices for software supply chain security
    Authors: Trevor Schiavone, Desiree Brunner | May 26, 2026
    Learn to apply AWS Well-Architected Framework security best practices to defend against software supply chain attacks like Shai-Hulud using temporary credentials, centralized dependency management, artifact signing, and continuous scanning.

    AWS Security Hub Extended: Why enterprise security products should sell themselves
    Author: Michael Fuller | May 20, 2026
    A thought leadership piece on how AWS Security Hub Extended enables frictionless, pay-as-you-go adoption of curated partner security solutions alongside AWS-native services.

    Application Security

    Five ways to use Kiro and Amazon Q to strengthen your security posture
    Author: Roger Nem | Published: May 5, 2026
    Learn to use Kiro and Amazon Q Developer for security finding triage, infrastructure remediation, security reviews, and service control policies (SCP) development.

    AWS Security Agent full repository code scanning feature now available in preview
    Authors: Ayush Singh, Daniele Bonadiman | May 12, 2026
    Learn to use AWS Security Agent’s full repository code review to perform deep, context-aware security analysis of your entire code base.

    Training and enablement

    Complimentary virtual training: Get hands-on with AWS Security services
    Author: Ashley Nelson | Published: May 11, 2026
    Security Activation Days are free 3–6 hour virtual workshops providing hands-on practice with AWS security services guided by specialists.

    May Security Bulletins

    Investigations of reported security vulnerabilities affecting Amazon and AWS services, software, and products.

    AWS Samples

    This month brings 8 new AWS samples spanning application security, data protection, infrastructure security, governance, and AI security. From AI-powered security agents on Amazon Bedrock AgentCore to centralized AWS Config monitoring at scale, these repositories help you implement security best practices across your AWS environment.

    Application Security

    Schedule AWS Security Agent penetration test
    Learn to deploy a AWS CloudFormation template that uses Amazon EventBridge and AWS Step Functions to schedule recurring AWS Security Agent penetration tests with Amazon Simple Notification Service
    (SNS) notifications on completion.

    Security review assistant
    Learn to deploy a multi-agent system on Amazon Bedrock AgentCore that automates Deliverable Security Reviews by combining architecture analysis, IaC code review, ASH vulnerability scanning, and compliance assessment into a single pipeline.

    AWS Security Agent Recorder
    Learn to use a cross-browser extension that records the unique domains your web app contacts and auto-fills them into the AWS Security Agent penetration test configuration.

    Data Protection

    KMS access audit
    Learn to resolve and report who can use your AWS Key Management Service (KMS) keys across IAM policies, key policies, and grants, with IAM Identity Center resolution to identify the humans behind SSO roles.

    Infrastructure security

    Building a conversational AI agent for AWS WAF analysis with AgentCore
    Learn to deploy an AI-powered agent using Amazon Bedrock AgentCore and Strands SDK that investigates AWS WAF security incidents, detects bypasses, and generates security reports through natural language.

    Governance

    Centralized AWS Config CI monitoring with Amazon CloudWatch
    Learn to centrally monitor AWS Config Configuration Item recording across all accounts in an AWS Organization using CloudWatch Cross-Account Observability, with dashboards showing top resource types, per-account volume, and conformance pack compliance.

    CloudFormation Guard security analyzer
    Learn to deploy an AI agent powered by Amazon Bedrock AgentCore that scans CloudFormation resource documentation, identifies security-critical properties with risk levels, and generates ready-to-use cfn-guard 3.x rules for your CI/CD pipeline.

    AI Security

    Guarded user-controlled attested runtime deployment (Guardian Platform)
    Learn to deploy LLM models securely in consumer AWS accounts while protecting model weights using AWS Nitro TPM attestation, KMS envelope encryption, and Zero Operator Access with immutable AMIs.

    AWS Labs

    This month brings 1 new AWS Labs repository focused on governance, helping research institutions deploy secure, tagged infrastructure with self-service access and multi-account controls.

    ResearchStack on AWS
    Learn to deploy research computing infrastructure on AWS in minutes — Amazon EC2, S3, EFS, Amazon SageMaker AI, and ParallelCluster — with built-in security, cost tracking, and governance using CloudFormation templates and optional AWS Service Catalog.

    Conclusion

    May 2026 shows AI security maturing from model-level controls to full-stack protection of agentic workflows. The posts and samples provide patterns for policy-based authorization with Cedar, network traffic filtering by category, and cross-account compliance monitoring. The security bulletins address vulnerabilities in SDKs, drivers, and developer tooling. Each resource includes deployment steps or runnable code so you can validate in your own environment before adopting. Subscribe to the AWS Security Blog RSS feed to receive updates as they publish, and revisit this digest monthly for a consolidated view of what changed and what to act on.

    If you have feedback about this post, submit comments in the Comments section below.


    Rodolfo Brenes

    Rodolfo is a Principal Solutions Architect focused on Cloud Governance and Compliance. With over 18 years of experience, he currently leads a technical field community in AWS helping customers scale and improve their security and governance frameworks. Besides work, Rodolfo enjoys video games, playing with his four cats, and won’t say no to a good outdoor adventure.

    Anna Brinkmann

    Anna has 18 years of experience in the technical content space and has spent the last 6 years managing the AWS Security Blog. Outside of work, she enjoys spending time with her family.

    Operationalizing AWS security: A maturity roadmap

    Post Syndicated from Joseph Sadler original https://aws.amazon.com/blogs/security/operationalizing-aws-security-a-maturity-roadmap/

    Enabling security tooling is the starting point. Making it operational—where findings drive decisions, response times are measurable, and your security posture improves week over week—is where most organizations struggle.

    This blog post provides a phased maturity roadmap for organizations that have already enabled AWS Security Hub and Amazon GuardDuty. These two services form the foundation of a cloud-centered security operations capability on AWS. Security Hub provides centralized security posture management and aggregates findings from multiple AWS security services, while GuardDuty provides intelligent threat detection by continuously monitoring for malicious activity and unauthorized behavior. For any production or enterprise AWS environment, having both services enabled across all accounts and AWS Regions is a baseline expectation; not because they’re optional add-ons, but because effective security operations require both the ability to detect threats and the ability to understand your overall security posture. If you haven’t yet enabled them, the Security Hub documentation and GuardDuty documentation provide setup guidance, including multi-account deployment with AWS Organizations.

    Customers consistently tell us that while individual AWS security service documentation is thorough, what’s missing is a consolidated operational playbook—one resource that ties the services together into a working security operations practice with clear phases, progression criteria, and an operational cadence. That’s the gap this post fills. Rather than covering how each feature works (the documentation does that well), this post focuses on when and why to use each capability, and how to build the organizational habits that make them effective.

    What follows is a six-phase roadmap for moving from these services are active to these services are driving our security operations. Each phase builds on the previous one, and each is designed to deliver tangible, measurable improvement.

    Phase 0: Assess your current state

    Goal: Understand what’s working before changing anything.

    Estimated timeline: 1–2 weeks

    Move to Phase 1 when: You have a documented current-state assessment covering all the following items.

    Before introducing new processes or automation, establish a clear picture of the current environment. This assessment informs every decision that follows.

    Actions:

    • Findings inventory: Review existing active GuardDuty findings to determine how many there are, the severity distribution, and how old the oldest findings are. A large backlog of untouched HIGH or CRITICAL findings that have been sitting for weeks is a strong signal about where to focus first.
    • Security Hub score baseline: Determine your current compliance score against AWS Foundational Security Best Practices (FSBP) and The CIS AWS Foundations Benchmark. Check to see which standards are enabled; if multiple standards are enabled, review for overlapping standards (creating noise) or unused standards.
    • Multi-account and multi-Region check: Look to see if GuardDuty is enabled in every account and every Region, or only in Regions with active workloads. Threat actors frequently operate in Regions that organizations don’t actively monitor. Also check to see if Security Hub aggregation is configured with a delegated administrator account or if each account is being managed independently.
    • Integration check: Determine if GuardDuty findings are flowing into Security Hub and if Amazon Inspector and Amazon Macie are enabled and feeding findings in. Without integration, Security Hub might be only surfacing its own compliance checks.
    • Notification check: See if there’s an Amazon EventBridge rule configured for notifications and if so, how findings are being routed and to whom. Know if notifications are being sent using an Amazon Simple Notification Service (Amazon SNS) topic or a chat channel integration. Without a clear notification and response workflow, findings can accumulate silently in the console with no one looking at them.

    Deliverable: A one-page current state assessment that identifies what’s enabled, what’s flowing where, who’s looking at it, and what’s in the existing backlog.

    Phase 1: Reduce the noise

    Goal: Make the signal meaningful before asking anyone to act on it.

    Estimated timeline: 2–3 weeks

    Move to Phase 2 when: Remaining findings represent items requiring real decisions, compliance scores reflect actual posture, and you can articulate why every suppression rule and disabled control exists.

    This is the single most important phase. If this step is skipped in favor of jumping straight to automation, the result is automated chaos. Alert fatigue is the primary reason security tooling is ignored, and addressing it first is what makes everything that follows sustainable.

    GuardDuty tuning:

    • Create suppression rules for known-benign findings. The goal is to suppress activity you’ve already evaluated and accepted—such as expected traffic from corporate egress IPs (based on trusted IP lists), internal tools that trigger DNS-based findings, or internet-facing resources that naturally receive port scanning. The principle: if you’ve investigated a finding and it’s expected, suppress it so your team can focus on what matters.
    • Triage every active HIGH and CRITICAL finding into three categories: needs immediate investigation (real threat, not yet reviewed), true positive, already addressed (archive using workflow status), or false positive or expected behavior (create a suppression rule). Every finding must be categorized into one of these three states.
    • Review GuardDuty protection plans and enable any that are relevant but not yet active. Organizations that enabled GuardDuty years ago might not have activated protection plans released since then (such as Runtime Monitoring, Malware Protection, RDS Protection, and Lambda Protection). Evaluate each against your workload profile and enable what applies.

    Security Hub tuning:

    • Disable controls that aren’t relevant to the environment. This is the highest-value quick win. If a service isn’t in use, disable its controls. If a control is addressed by an alternative solution, disable it. A 47% compliance score where half the failures are irrelevant trains teams to ignore the dashboard entirely. See the Security Hub controls reference for the full list.
    • Choose a primary standard. AWS Foundational Security Best Practices is a strong default. The CIS AWS Foundations Benchmark adds value when there’s a specific compliance mandate. Avoid enabling PCI DSS or NIST 800-53 standards unless there’s a reporting requirement—they add significant volume without proportional signal for most organizations.
    • Configure cross-Region aggregation to the delegated administrator account if not already in place. A single aggregated view eliminates the need to check findings across multiple Regional consoles.
    • Use the workflow status field operationally. Findings should progress from NEW to NOTIFIED to RESOLVED or SUPPRESSED. If everything remains in NEW indefinitely, the system carries no operational meaning.

    Deliverable: A tuned environment where remaining findings represent items that require real decisions. Compliance scores should now reflect your organization’s actual security posture rather than noise.

    Phase 2: Build the notification and routing layer

    Goal: Get the right findings to the right people at the right time.

    Estimated timeline: 2–3 weeks

    Move to Phase 3 when: CRITICAL and HIGH findings reach the security team within minutes, MEDIUM findings create tracked tickets, and notifications include enriched context. No action is taken until a person or an automation is informed that something needs attention.

    Architecture: Security Hub to EventBridge rule to routing logic to destination

    Tiered notification strategy:

    CRITICAL Page on-call immediately PagerDuty or Opsgenie 15 minutes
    HIGH Alert security team channel Slack or Teams channel and ticket creation 4 hours
    MEDIUM Create ticket for review Jira or ServiceNow 48 hours
    LOW or INFORMATIONAL Batch digest Weekly email summary or dashboard review Next review cycle

    Key design decisions:

    • Route from Security Hub, not individual services. Because findings from GuardDuty, Inspector, Macie, and Security Hub compliance checks all aggregate in Security Hub, build your EventBridge rules there for centralized management.
    • Create a fast path for the most dangerous finding types. Certain GuardDuty findings, particularly those involving credential exfiltration, cryptocurrency activity, trojans, and active compromises, warrant a separate, faster routing path that bypasses normal triage. Identify these based on your threat model and the GuardDuty finding types reference.
    • Enrich notifications before delivery. A raw JSON finding in a chat channel provides little actionable context. Use an AWS Lambda function to format notifications with the information responders need: account alias, Region, Amazon Resource Name (ARN), finding type, severity, a console deep link, and a plain-language description. The Security Hub CloudWatch Events integration guide describes the event format.

    Deliverable: A working notification pipeline where CRITICAL and HIGH findings reach the security team within minutes, MEDIUM findings create tracked work items, and LOW and INFORMATIONAL findings are batched for periodic review.

    Phase 3: Build automated remediation for high-confidence findings

    Goal: For findings where the correct response is deterministic, remove the human from the loop.

    Estimated timeline: 3–4 weeks

    Move to Phase 4 when: At least 3–5 high-confidence finding types have automated responses deployed with audit trails, and the team has established a process for evaluating new auto-remediation candidates.

    The guiding principle: Only auto-remediate when all three conditions are met: the finding is high-confidence, the response is deterministic, and the blast radius of the automated action is limited. Automated remediation must not create the risk of a production outage.

    Decision framework:

    Confidence level High – no false positive risk Medium – context-dependent Low – requires investigation
    Response complexity Single, well-defined action Multiple steps or judgment calls Requires forensic analysis
    Blast radius Limited to one resource Could affect dependent services Production-wide impact
    Rollback difficulty Straightforward to reverse Moderate effort to reverse Difficult or impossible to reverse

    Common auto-remediation categories:

    • Instance isolation for confirmed compromise findings (cryptocurrency mining, malware, and trojans): Replace the security group, snapshot volumes for forensics, and notify.
    • Credential revocation for confirmed credential compromise: Attach deny-all policies, revoke sessions, and deactivate access keys as appropriate to the credential type.
    • Compliance drift correction for deterministic misconfigurations: Re-enable Amazon Simple Storage Service (Amazon S3) Block Public Access, revoke overly permissive security group rules, and re-enable AWS CloudTrail logging.
    • Notification-only escalation for findings that require human judgment before action: Amazon Elastic Block Store (Amazon EBS) encryption gaps (require migration) and access key rotation (requires coordination with the key owner).

    For implementation, AWS provides Security Hub Automated Response and Remediation (SHARR), a solution that includes pre-built remediation playbooks deployed as AWS Step Functions workflows triggered by EventBridge. This is a strong starting point—evaluate the provided playbooks, enable the ones that fit, and extend with custom remediations as needed.

    Note: For findings that recur because the environment lacks preventive guardrails, the best long-term response is often a service control policy (SCP) that prevents the misconfiguration from occurring in the first place. Phase 5 covers this preventive controls layer.

    Deliverable: A library of automated and semi-automated remediation runbooks with full audit trails, and a documented decision framework the team uses to evaluate new auto-remediation candidates.

    Phase 4: Build the operational rhythm

    Goal: Turn security findings management into a sustained organizational practice, not a one-time cleanup.

    Estimated timeline: 4–6 weeks to establish, then ongoing

    Move to Phase 5 when: The weekly cadence has been running consistently for at least 8 weeks, monthly metrics show positive trends, and the first quarterly review has been completed.

    This is where many organizations stall, and it’s the most important phase in the entire roadmap. The technology is working, the notifications are flowing, automated remediations are firing, but there’s no organizational habit built around it. Without this phase, everything you’ve built in Phases 0–3 will gradually decay. Suppression rules will go stale, new team members won’t know the system exists, and findings will start accumulating again. The operational rhythm is what converts a security tooling deployment into a security operations practice.

    Weekly security review (30 minutes)

    Attendees: Security team lead, cloud platform team representative, rotating engineering lead from an application team

    Why the rotating engineering lead matters: Security findings don’t exist in a vacuum; they’re generated by workloads that engineering teams own. Rotating an engineering representative through this meeting accomplishes three things: it builds security awareness across the organization, ensures findings are routed to people with the context to resolve them, and creates organizational accountability beyond the security team.

    Agenda template:

    5 minutes Compliance score trend – Review Security Hub scores by account and standard. Is the trend improving, declining, or flat? If declining, why? Security lead Identified regression areas
    5 minutes Critical and high findings review – Walk through new HIGH and CRITICAL GuardDuty findings from the past week. Are there any that need immediate escalation? Security lead Escalation actions assigned
    10 minutes Top five failing controls – Identify the five Security Hub controls with the most failures. Assign an owner and a target date for each. Platform lead Owners and dates documented
    5 minutes Automation review – Did any auto-remediations fire this week? Did they work correctly? Were there any false triggers? Security lead Automation adjustments queued
    5 minutes Tuning decisions – Are new suppression rules needed based on this week’s findings? Are any new finding types candidates for auto-remediation? All Tuning backlog updated

    Running the meeting effectively:

    • Keep a running document (such as a wiki page or shared document) that captures decisions and action items week over week. This becomes your institutional memory.
    • If the compliance score hasn’t moved in over 3 weeks, that’s a signal. Either the assigned work isn’t happening, or the remaining findings are genuinely difficult to address. Both need to be discussed.
    • Track action items from previous weeks. A review that generates action items but never follows up on them will lose credibility and attendance quickly.

    Escalation procedures

    Define clear escalation paths before they’re needed:

    CRITICAL finding not acknowledged within the SLA Auto-escalate to security team manager 15 minutes after SLA breach
    HIGH finding not resolved within the SLA Escalate to finding owner’s manager 4 hours after SLA breach
    Compliance score drops more than 5 points in a week Escalate to cloud platform team lead for investigation Next business day
    Auto-remediation failure Page security on-call Immediate
    New finding type not covered by existing runbooks Add to weekly review agenda for triage and runbook development Next weekly review

    Monthly metrics report

    Compile these metrics monthly and review them with security and engineering leadership. The goal is to tell a story about whether the organization’s security posture is improving, stable, or degrading, and why.

    Mean time to acknowledge (MTTA) for CRITICAL findings Are findings being seen promptly? Decreasing month over month
    Mean time to resolve (MTTR) for CRITICAL and HIGH findings Are findings being acted on? Decreasing month over month
    Security Hub compliance score by standard, by account What is the posture trend over time? Increasing month over month
    Number of active GuardDuty findings by severity Is the backlog growing or shrinking? Decreasing for HIGH and CRITICAL
    Findings auto-remediated compared to manually resolved Is automation delivering value? Auto-remediation ratio increasing
    Number of suppressed findings (with quarterly justification review) Is noise being managed, or are problems being hidden? Stable or decreasing
    New findings introduced compared to resolved this month Is the organization getting ahead or falling behind? More finding resolved than introduced
    SLA adherence rate by severity Are response commitments being met? More than 95% for CRITICAL, and more than 90% for HIGH

    Building the dashboard: Use Amazon CloudWatch dashboards for real-time operational visibility or Amazon QuickSight connected to Security Hub findings through Amazon Security Lake for historical trend analysis and executive reporting. The dashboard should be visible to—and regularly viewed by—everyone in the weekly review, not locked in a security team tool.

    Quarterly reviews

    The quarterly review is a deeper inspection of the system itself; not just the findings, but the machinery processing them.

    Quarterly review checklist:

    • Suppression rules audit: Review every active suppression rule to determine if the underlying condition is still present and the suppression is still justified. Document the review outcome for each rule.
    • Disabled controls audit: Review every disabled Security Hub control. Check that the justification is still valid and if the environment changed (for example, a service that wasn’t in use is now in use).
    • Automation audit: Review AWS Identity and Access Management (IAM) roles used by remediation functions and verify least privilege. Review execution logs for any anomalies or failures that weren’t caught.
    • New capabilities review: Evaluate newly released GuardDuty protection plans and Security Hub controls from that quarter. AWS releases new detection and compliance capabilities regularly. If you’re not reviewing them quarterly, you’re accumulating blind spots.
    • Process effectiveness review: Determine if the weekly meeting is well-attended and if action items are being completed. Make sure SLAs are being met. If attendance, action item completion, and SLA compliance aren’t where they should be, explore structural changes to address the gaps.

    Operational maturity scoring

    Use this rubric to assess the maturity of your operational rhythm itself. Score each dimension 1–3 and use the total to track progress over time.

    Review cadence One time reviews when someone remembers Weekly review happens, but attendance is inconsistent Weekly review is consistently attended with documented outcomes
    Metrics tracking No metrics captured Metrics are collected monthly but not acted on Metrics drive decisions and declining trends trigger specific actions
    Finding ownership Findings sit in queue with no owner Findings are assigned to teams but SLAs aren’t tracked Every finding has an owner, SLAs are tracked, and breaches are escalated
    Automation management Set-and-forget automations Automation logs are reviewed periodically Automation is reviewed weekly, and new candidates are evaluated continuously
    Tuning lifecycle Suppression rules created but never reviewed Annual review of suppressions and disabled controls Quarterly reviews with documented justification for every rule
    Cross-team engagement Security team works in isolation Platform team participates Engineering teams actively participate and own remediation

    Scoring (revisit quarterly):

    • Beginning: 6–9
    • Established: 10–14
    • Optimized: 15–18

    Deliverable: A documented operational cadence with clear ownership (consider a RACI matrix), metrics dashboards, escalation procedures, and a continuous improvement loop. The cadence should survive team member turnover—if it depends on one person remembering to run it, it’s not yet operational.

    Phase 5: Mature the architecture

    Goal: Fill remaining gaps and build toward a comprehensive security operations capability. Estimated timeline: Ongoing. Prioritize based on organizational risk profile and compliance requirements.

    • Amazon Inspector integration: Enable Amazon Inspector for Amazon Elastic Compute Cloud (Amazon EC2) instances, Lambda functions, and Amazon Elastic Container Registry (Amazon ECR) container images. Findings flow into Security Hub automatically, adding vulnerability management alongside threat detection and posture management. Prioritize this if you have Amazon EC2 or container workloads without an existing vulnerability scanning solution.
    • Amazon Macie: Enable Amazon Macie for S3 buckets containing potentially sensitive data. Particularly important for organizations with compliance requirements around personally identifiable information (PII), protected health information (PHI), or Payment Card Industry (PCI) data. Configure automated sensitive data discovery and route findings to Security Hub.
    • Amazon Security Lake: Amazon Security Lake centralizes security-relevant logs in OCSF format for long-term retention, forensic investigation, and threat hunting. This is valuable when you need historical analysis beyond the Security Hub retention window, or when feeding a third-party Security Information and Event Management (SIEM) tool.
    • Preventive controls layer: Convert recurring detective findings into preventive policies. Use SCPs to prevent disabling GuardDuty, Security Hub, and CloudTrail, IAM permission boundaries on developer roles, AWS WAF on public endpoints, and AWS Network Firewall for VPC traffic inspection. The pattern is to make recurring misconfigurations impossible to introduce.
    • Detective controls expansion: Use AWS IAM Access Analyzer for external access and unused access findings, AWS CloudTrail Lake for long-term queryable audit logs, and AWS Config custom rules for organization-specific compliance checks.
    • Incident response readiness: Have incident response playbooks referencing specific GuardDuty finding types, pre-built forensics infrastructure (isolated VPC, forensic AMIs, and pre-configured IAM roles), regular tabletop exercises, and AWS CloudFormation templates to deploy isolation infrastructure on demand. See the AWS Security Incident Response Guide for a comprehensive framework.

    Conclusion

    In this post, I provided a six-phase roadmap for operationalizing Security Hub and GuardDuty and showed that it isn’t a single project, but a progression. Phase 0 and Phase 1 can typically be completed in 3–5 weeks and deliver immediate clarity. Phases 2 and 3 build the response infrastructure that turns findings into action over the following 5–7 weeks. Phase 4 is what makes everything sustainable and is where you should invest the most attention. And Phase 5 expands the aperture from Security Hub and GuardDuty into a comprehensive security operations capability.

    If you walked away from this post and did one thing, run the Phase 0 assessment this week. That single deliverable tells you exactly where to focus next. Use the following self-assessment checklist to identify your current phase, then focus on the next one. A tuned environment with working notifications and a weekly review cadence is dramatically more effective than a fully featured but neglected deployment. Start where you are, reduce the noise, build the habits, and iterate. To learn more, explore the AWS Security Hub User Guide, the Amazon GuardDuty User Guide, and the AWS Security Incident Response Guide. If you’ve implemented a similar operational cadence, or have questions about any phase, share your experience in the comments.

    Self-assessment checklist

    Phase 0 We know how many active GuardDuty findings exist across all accounts
    We know our current Security Hub compliance score
    We know whether GuardDuty is enabled in every account and region
    We know who (if anyone) is reviewing findings today
    Phase 1 GuardDuty suppression rules exist for known-benign activity
    Irrelevant Security Hub controls have been disabled with documented justification
    All active HIGH and CRITICAL findings have been triaged
    Security Hub compliance scores reflect actual posture, not noise
    Phase 2 HIGH and CRITICAL findings generate real-time notifications to the security team
    MEDIUM findings automatically create tracked work items
    Notifications include enriched context (account alias, resource ARN, and console link)
    Phase 3 At least three high-confidence finding types trigger automated remediation
    Auto-remediation actions have full audit trails
    Remediation runbooks are documented and version-controlled
    Phase 4 A weekly security review meeting occurs with defined attendees and agenda
    MTTA and MTTR are tracked monthly for CRITICAL and HIGH findings
    Suppression rules and disabled controls are reviewed quarterly
    Security metrics trend positively over the past 3 months
    Phase 5 Amazon Inspector, Macie, or Security Lake are integrated
    Preventive controls (SCPs, permission boundaries) address recurring findings
    Incident response playbooks exist and are tested through tabletop exercises

    If you have feedback about this post, submit comments in the Comments section below.


    Joseph Sadler

    Joseph Sadler

    Joseph is a Senior Solutions Architect on the Worldwide Public Sector team at AWS, specializing in cybersecurity and machine learning. With public and private sector experience, he has expertise in cloud security, artificial intelligence, threat detection, and incident response. His diverse background helps him architect robust, secure solutions that use cutting-edge technologies to safeguard mission-critical systems

    Building secure B2C applications with fine-grained access control using Amazon Cognito and Amazon Verified Permissions

    Post Syndicated from Sowmya Vemuri original https://aws.amazon.com/blogs/security/building-secure-b2c-applications-with-fine-grained-access-control-using-amazon-cognito-and-amazon-verified-permissions/

    Modern web applications require robust security controls to protect user data and application resources. Authentication and authorization are two fundamental pillars of application security that answer critical questions: Who are you? and What are you allowed to do? Implementing these controls correctly can be challenging for developers, especially when building data-intensive applications with frameworks like Streamlit (an open-source Python framework for building interactive web applications) or when requiring fine-grained access control. Key challenges include protecting access to application resources, implementing application identity with multi-factor authentication (MFA), and implementing usage-based controls.

    In this post, you will learn how to build fine-grained access controls for a sample Streamlit application using Amazon Cognito for authentication and Amazon Verified Permissions with Cedar policies for authorization. This architecture provides enterprise-grade security with minimal development effort, so you can focus on your application’s core functionality. You will learn how to reduce development time for secure applications, implement enterprise-grade authentication, through proper access management, and scale security with growing user bases.

    Security architecture overview

    The reference architecture follows a layered security design with four key components; separating identity verification, authorization evaluation, application logic, and enforcement boundaries. By assigning clear responsibilities to each layer, the architecture limits blast radius and ensures that a failure in any single control does not compromise the overall system.

    • Authentication layer: Amazon Cognito handles user authentication with secure credential validation and JSON web tokens (JWTs). It provides built-in password policies, account lockout protection, and session management.
    • Authorization layer: Verified Permissions uses the Cedar policy engine to evaluate fine-grained access requests based on centrally stored policies.
    • Application layer: The Streamlit frontend integrates with both services, managing user sessions and enforcing access controls in the user interface.
    • Security boundaries: Multiple layers of security controls protect against unauthorized access, privilege escalation, authentication verification, authorization checks, and input validation.

    This separation of concerns enables authentication and authorization to function as complementary security controls, following defense-in-depth principles. Figure 1 illustrates the end-to-end authentication and authorization workflow, showing how a user’s sign-in request flows through Amazon Cognito for identity verification, then through Verified Permissions for Cedar policy-based access decisions, before the application enforces the result.

    Figure 1: Solution architecture and workflow

    Figure 1: Solution architecture and workflow

    The following workflow demonstrates how the three architecture layers work together: the authentication layer (steps 1–3) handles identity verification using Amazon Cognito, the authorization layer (steps 4–6) evaluates Cedar policies using Verified Permissions, and the application layer (steps 7–8) enforces the decision in Streamlit.

    1. The user sends a sign-in request, which is submitted through Streamlit
    2. The request is authenticated by Amazon Cognito
    3. An access token is sent back to Streamlit
    4. An authorization request is sent to Verified Permissions
    5. The Cedar policy engine evaluates the request
    6. A decision is sent back by the policy engine
    7. The instruction to allow or deny is sent back to Streamlit
    8. If the instruction is to allow, access is provided

    Understanding authorization with Cedar

    While authentication establishes user identity, authorization determines what actions users can perform. Verified Permissions provides a scalable authorization service based on Cedar, a policy language specifically designed for fine-grained access control.

    Cedar policies follow a structured format that defines who can perform which actions on what resources. Let’s examine the anatomy of a Cedar policy:

    permit(
        principal == ?principal,
        action == application::Action::"ViewGrade",
        resource == ?resource
    ) when {
        principal has role == "Student" &&
        resource.student == principal.entityId
    };

    Policy components

    • Effectpermitor forbid determines whether the policy allows or denies access
    • Principal: The entity (user) making the request, represented by ?principal as a variable
    • Action: The operation being performed, scoped to your application namespace
    • Resource: The target of the action, also represented as a variable
    • Conditions: The when clause contains logical expressions that must evaluate to true

    Advanced Cedar policy patterns

    This section describes commonly used Cedar policy patterns for implementing fine-grained authorization with Amazon Verified Permissions. The examples illustrate how to model ownership, role-based access, hierarchical permissions, and administrative controls in real-world applications

    Resource ownership control

    This pattern helps ensure that users can only access resources they own:

    permit(
        principal == ?principal,
        action == application::Action::"ViewGrade",
        resource == ?resource
    ) when {
        principal has role == "Student" &&
        resource.student == principal.entityId
    };

    What it does – This policy allows students to view only their own grades by:

    • Checking that the user has the Student role
    • Verifying that the grade resource’s student attribute matches the student’s entityId
    • Preventing students from accessing other students’ grades while allowing access to their own academic performance

    Role-based access with resource type

    This pattern grants access based on role and resource type:

    permit(
        principal == ?principal,
        action == application::Action::"EditCourse",
        resource == ?resource
    ) when {
        principal has role == "Faculty" &&
        resource has resourceType == "Course" &&
        resource.instructor == principal.entityId
    };

    What it does – This policy allows faculty members to edit courses they teach by:

    • Verifying the user has the Faculty role
    • Confirming the resource is of type Course
    • Verifying that the course’s instructor attribute matches the faculty member’s entityId
    • Restricting faculty to modify only their own courses, not courses taught by other instructors

    Hierarchical authorization

    This pattern allows department heads to manage faculty in their department:

    permit(
        principal == ?principal,
        action == application::Action::"ManageFaculty",
        resource == ?resource
    ) when {
        principal has role == "DepartmentHead" &&
        resource has role == "Faculty" &&
        resource.department == principal.department
    };

    What it does – This policy implements departmental hierarchy controls by:

    • Requiring the user to be a DepartmentHead
    • Verifying the resource is a faculty member
    • Matching the faculty member’s department with the department head’s department
    • Preventing department heads from managing faculty in other departments

    Administrative override

    This pattern provides emergency access with proper justification:

    permit(
        principal == ?principal,
        action == ?action,
        resource == ?resource
    ) when {
        principal has role == "Administrator" &&
        context has emergencyAccess == true &&
        context has justification
    };

    What it does – This policy provides emergency access capabilities by:

    • Allowing administrators to perform any action on any resource
    • Requiring an emergency access flag to be set to true
    • Requiring a justification for emergency access
    • Supporting accountability through required documentation while enabling emergency operations

    Cedar policy evaluation flow

    Understanding how policies are evaluated helps design effective authorization systems. Figure 2 shows a common evaluation pattern for an academic scenario

    Note: A policy match evaluates to the policy’s effect (permit or forbid). Forbid policies take precedence: if any forbid policy matches, access is denied regardless of permit policies.

    Figure 2: Policy evaluation process

    Figure 2: Policy evaluation process

    The policy evaluation process follows these steps:

    1. User attempts to access a protected resource
    2. Application sends an authorization request to Verified Permissions
    3. Verified Permissions retrieves applicable Cedar policies from the policy store
    4. The Cedar policy engine evaluates each policy against the request
    5. If any forbid policy matches, access is denied immediately
    6. If any permit policy matches and no forbid policies match, access is allowed
    7. If no policies match, access is denied by default
    8. The evaluation result (ALLOW or DENY) is returned to the application
    9. Application enforces the authorization decision

    Cedar policy language

    Cedar is an Amazon open source policy language designed for fine-grained authorization. Every policy defines who (principal) can perform what action on which resource under what conditions, as shown in Figure 3.

    Figure 3: Cedar policy definitions

    Figure 3: Cedar policy definitions

    Policy interaction

    The following table shows how different policies interact in complex scenarios where multiple policies could apply:

    Scenario Student policy Faculty policy Department head policy Admin policy
    Student accessing own grade Permit N/A N/A Override
    Faculty editing course N/A Permit N/A Override
    Department head managing faculty N/A N/A Permit Override
    Emergency admin access N/A N/A N/A Permit

    Legend:

    • Permit – Policy allows access
    • N/A – Policy doesn’t apply
    • Override – Emergency admin access

    The preceding table shows how each role’s policy applies to different scenarios, with admin access having override capabilities across most situations except for emergency admin access where it’s the primary permit authority. The Override column specifically indicates that the administrator’s emergency access policy can supersede other role-specific policies, but only when the emergencyAccess context flag is explicitly set and a justification is provided. This is not an automatic override.

    Policy optimization tips:

    • Order conditions by likelihood of success – Place the most frequently true conditions first in your when clause to enable short-circuit evaluation. For example, check role before resource ownership, because role mismatches are caught earlier. See Cedar best practices.
    • Use indexed attributes for faster lookups – Use entity attributes that Verified Permissions indexes natively (entityId, role, resource type) as primary conditions. Best practices for designing an authorization model
    • Cache policy evaluations when appropriate
    • Monitor evaluation metrics and performance

    Real-world application: Academic system

    Consider an academic system with different user roles and their corresponding permissions:

    Student: View own grades

    • Policy helps ensure students can only access grade resources where they are listed as the student
    • The policy verifies the student’s role and matches the resource owner to the principal’s entity ID

    Faculty: Edit course content, manage grades

    • Policy allows faculty to edit courses they teach
    • Faculty can view and modify grades for students in their courses

    Teaching assistant (TA): Grade management and course support

    • Policy permits TAs to manage grades for courses they assist with
    • Access is limited to specific courses assigned to the TA

    Department head: Manage faculty assignments

    • Policy allows department heads to manage faculty in their department
    • Access is scoped to the department hierarchy

    Administrator: System-wide access

    • Policy provides emergency access with proper justification
    • Administrative actions are logged and audited

    Prerequisites

    To implement the preceding Academic system application, you need an active AWS account, Python 3.8 or later, basic Streamlit knowledge, and AWS Identity and Access Management (IAM) permissions for Amazon Cognito and Verified Permissions.

    Run the sample and extend the solution

    1. Download the code base: Start by downloading the code base from the avp streamlit samples repository
    2. Set up your development environment: Install the AWS SDK for Python (boto3) and configure your AWS credentials.
      • Install the AWS SDK for Python:
        pip install boto3
        

      • Log in to your AWS account:
        aws login --region $REGION

      • Verify that your AWS Command Line Interface (AWS CLI), Python, and dependencies are correctly configured.
        ./verify-setup.sh

    3. Create your AWS resources: Use the AWS Management Console or infrastructure as code (IaC) tools to provision your Amazon Cognito user pool and Verified Permissions policy store.
      ./deploy-demo-environment.sh
      Do you want to start the demo now? (Y/N): Y

      This provisions an Amazon Cognito user pool, a Verified Permissions policy store, and any sample resources needed for the demo.

    4. Verify the login screen:
      Figure 4: Verify login credentials

      Figure 4: Verify login credentials

    5. Demo walkthrough and shut down: Interact with the demo and test the policies and features. When you’re ready to exit, press Ctrl+C to shut down and stop.
    6. Define your Cedar policies: Start with basic policies and gradually add complexity as you understand the evaluation model.
    7. Implement authentication: Integrate Amazon Cognito authentication into your application with proper error handling.
    8. Add authorization checks: Implement authorization checks at critical access points in your application. For authentication, implement proper error handling for expired tokens, failed MFA challenges, and account lockouts. Use the Amazon Cognito built-in token refresh flow. For authorization, place Verified Permissions checks at every API endpoint and UI component that accesses protected resources.
    9. Test thoroughly: Create test scenarios for each user role and permission combination.
    10. Monitor and iterate: Set up AWS CloudTrail logging and Amazon CloudWatch alarms to monitor your security controls and refine them based on real-world usage.

    Security best practices

    When implementing this architecture, follow these best practices to support security:

    • Layer your security controls: Use both authentication and authorization as complementary controls rather than relying on a single mechanism.
    • Follow least privilege principles: Grant only the permissions needed for specific user roles. Start with minimal permissions and add more as needed.
    • Implement proper session management: Set appropriate token expiration and refresh policies. Amazon Cognito handles much of this automatically, but you should configure timeouts based on your security requirements.
    • Validate all inputs: Sanitize user inputs to prevent injection attacks. Don’t rely on client-side validation alone.
    • Monitor authentication events: Set up logging and alerts for suspicious activities such as repeated failed login attempts or unusual access patterns.
    • Conduct regular security reviews: Periodically audit your policies and security configurations to verify they still meet your requirements and follow current best practices.
    • Implement secure error handling: Avoid information disclosure through error messages. Provide helpful feedback to users without revealing system details that could aid attackers.

    Conclusion

    Implementing proper authentication and authorization is critical for application security. By using Amazon Cognito and Amazon Verified Permissions, you can build robust security controls without complex custom code. Through this approach, you can implement enterprise-grade authentication with minimal effort, define and enforce fine-grained authorization policies, scale your security controls as your application grows, and centrally manage and audit security policies.

    To get started with your implementation, create your AWS resources including an Amazon Cognito user pool and Verified Permissions policy store. Define your Cedar policies based on your application’s access requirements. Integrate authentication and authorization checks into your application flow. Test thoroughly with different user roles and access scenarios. Finally, monitor and refine your security controls based on usage patterns.

    For additional resources, check out the Amazon Cognito documentation and Amazon Verified Permissions documentation.

    If you have feedback about this post, submit comments in the Comments section below.


    Sowmya Vemuri

    Sowmya Vemuri

    Sowmya is a Senior Technical Customer Solutions Manager at AWS, where she partners with AWS’s largest customers to drive agentic AI transformation, cloud security strategy, and compute modernization at scale. She has 14+ years of engineering, product, and technical leadership experience building and scaling distributed systems across the stack: bare-metal servers, data platforms, enterprise and consumer applications, and autonomous cloud architectures with zero human operator access.

    Amazon Cognito unlocks advanced capabilities with next-generation infrastructure

    Post Syndicated from Howie Li original https://aws.amazon.com/blogs/security/amazon-cognito-unlocks-advanced-capabilities-with-next-generation-infrastructure/

    Amazon Cognito recently introduced high-throughput performance for demanding workloads, customer-managed keys for full control over data encryption at rest, and multi- Region replication for business continuity improvement. These capabilities were made possible through a next-generation storage infrastructure designed for extensibility and scale. To deliver this, we migrated hundreds of millions of user profiles, and you probably didn’t even notice. In this post, we walk through what’s new, the architecture behind it, and how we got here with a zero-downtime migration that kept your applications running.

    New capabilities now available on Cognito

    The migration to the new infrastructure wasn’t just about maintaining existing functionality—it created the foundation for delivering capabilities that solve customer challenges while positioning Amazon Cognito for continuous improvements.

    High-throughput performance: The new architecture supports the higher request volumes and scale requirements of modern applications while maintaining the low latency performance that your applications depend on—able to support tens of millions of users per user pool and thousands of transactions per second (TPS).

    Customer-managed keys: Customers can now use their own encryption keys stored in AWS Key Management Service (AWS KMS) for encrypting data at rest. This provides enhanced security control and capabilities, giving customers full ownership over their encryption key lifecycle.

    Multi-Region replication: Customers can now synchronize their entire user pool data, including user passwords, attributes, and configurations to another user pool in another Region of their choice. This means that customers can implement business continuity strategies and maintain authentication availability in case of a Regional failover, helping their applications remain accessible to users even during unexpected disruptions.

    An architecture for innovation

    The new architecture uses a purpose-built storage layer designed for extensibility and scale of identity operations. We anchored the new architecture around a set of design tenets:

    • Identity-first design: The storage layer understands user identities. There’s no client-specific business logic and no generalizations beyond identity management; keeping the system focused, portable, and optimized.
    • Avoid one-way doors: Deliver value incrementally while keeping architectural choices reversible, so we can evolve as new needs arise.
    • Backward compatible: Changes to the underlying infrastructure should never break customers’ applications.

    These tenets shaped every architectural decision. The architecture separates into independently deployable domains. Previously, while using Amazon Cloud Directory, the service architecture relied on a single data store to persist all customer information. This provided straightforward data traversal mechanisms but required multi-service coordination to adjust database schema when new features were required. The new architecture uses different datasets, allowing them to evolve independently for faster feature iterations.

    Migration with zero-downtime

    Migrating users requires extreme precautions and a strategy designed to maintain zero downtime and ensure data integrity at every step. Our approach prioritizes both immediate stability and long-term flexibility through the following measures:

    1. Shadow mode validation: We ran customer API requests through both old and new infrastructures simultaneously, comparing response structures, status codes, and behavioral characteristics. The validation was designed so that sensitive information was never exposed in plaintext during comparison. We accounted for known variances—for example, timestamps could differ slightly between systems—so that only meaningful discrepancies surfaced as actionable alerts.
    2. Data backfill: Before switching a user pool to the new infrastructure, we performed a bulk backfill of all existing user records from the legacy system into the new storage. The backfill ran alongside live traffic with dual-write capturing any changes made during the backfill window, ensuring no data loss or stale data. Shadow mode served as the validation layer for the backfill; as we addressed more edge cases in data syncing, shadow mode match rates increased, confirming data completeness before we proceeded to the switchover.
    3. Dual-write architecture: We implemented a system where all identity operations were simultaneously written to both legacy and new services, with comprehensive validation to ensure consistency. Even when a dual-write to the new infrastructure failed, the operation still succeeded in the legacy system, preserving all customer-initiated requests. This means any dual-write failure was contained as an internal consistency issue and not customer-impacting.
    4. Antientropy validation: We implemented a data validation and correction system that continuously compared records across old and new infrastructures, detecting and resolving any data divergence. Anti-entropy scans compared user attributes, credential hashes, group memberships, and configurations, among other records. When true discrepancies were found, the system automatically reconciled them using the legacy system as the source of truth. This layer was able to catch edge cases that shadow mode and dual writes alone could not cover.
    5. Incremental rollout with rollback capability: We established controlled deployment phases with immediate rollback capabilities. After switching a user pool to the new infrastructure, we continued replicating all writes back to the legacy system, ensuring we can revert any user pool to the legacy infrastructure at any point without data loss. If a rollback was needed during migration, an orchestrator replayed entries in timestamp order, syncing user profiles back to the legacy system.

    Lessons learned for infrastructure modernization

    This modernization taught us valuable principles that apply to any large-scale infrastructure project, therefore we choose to share these learnings to help you perform similar migrations.

    • Customer access patterns drive architecture decisions: Analyzing actual customer access patterns revealed that identity workloads follow predictable patterns, which meant we could adopt a synchronous dual-write approach that balanced completeness with operational simplicity. This principle applies to any domain-specific migration: understand your workload’s actual access patterns before reaching for general-purpose solutions.
    • Behavioral preservation requires techniques beyond traditional testing: Ensuring equivalent functionality across old and new systems was straightforward. Preserving identical API behavior was not. Functional tests validate intended behaviors, but we identified scenarios where customers had built applications around specific API behaviors such that a change could have silently broken their applications. For example, concurrent writes to the same user could resolve to different final states between old and new systems where writes all succeed but outcome diverges slightly. Similarly, customers who write an attribute and immediately read it are affected by the consistency window. Subtle timing differences in when updates become visible could cause stale reads. These aren’t functional failures, but behavior under real traffic patterns can vary. Shadow mode verification surfaced edge cases that automated tests alone would have missed. Invest in these techniques early.
    • Gradual validation builds confidence that testing alone cannot: Layer multiple independent validation techniques, such as shadow mode, dual writes, and anti-entropy scans—each covering a different access pattern. No single approach will catch everything, and the gaps between them are where production issues hide. Incremental rollout with immediate rollback capability lets you validate each step while maintaining the ability to revert quickly.
    • Key principles for your own modernization projects: Invest in purpose-built solutions, design for extensibility, and implement gradual validation. Or use managed services so your infrastructure improves without effort on your part while your applications keep running; helping you focus on your business needs.

    Conclusion

    In this post, we shared the high-level approach and learnings from the Amazon Cognito infrastructure modernization that create a foundation for modern identity management capabilities. The new Cognito infrastructure is live, delivering capabilities such as customer-managed keys and multi-Region replication. As the migration continues, all Cognito customers will gain access to these capabilities on the same service they rely on today, with no action required.

    Ready to modernize your authentication infrastructure? Visit Amazon Cognito to learn more.

    If you have feedback about this post, submit comments in the Comments section below.

    Howie Li

    Howie Li

    Howie is a Product Manager at Amazon Web Services, where he strives to make auth easy by default. Outside of work, Howie enjoys exploring cultures and food through travels and making new ice cream flavors inspired by them.

    Georgi Baghdasaryan

    Georgi Baghdasaryan

    Georgi is a Principal Engineer at Amazon Web Services, where he builds identity systems that help organizations securely manage access and authentication at scale. His broader focus is on reliable, high-impact infrastructure that enables customers to operate confidently in the cloud. Outside of work, Georgi enjoys experimenting with new matcha latte recipes and going on long bike rides.

    Gain visibility into DDoS attacks with flow logs in AWS Shield Advanced

    Post Syndicated from Ken Kitts original https://aws.amazon.com/blogs/security/gain-visibility-into-ddos-attacks-with-flow-logs-in-aws-shield-advanced/

    Reconstructing distributed denial of service (DDoS) attack traffic used to mean combining data from multiple sources after the fact. AWS Shield Advanced attack flow logs change that—they capture traffic metadata during attacks so you can pinpoint sources, verify mitigations, and feed your existing analysis pipelines.

    Shield publishes logs to Amazon Simple Storage Service (Amazon S3), Amazon CloudWatch Logs, or Amazon Data Firehose using the same CloudWatch Logs delivery infrastructure as other AWS flow logs, so they fit directly into the monitoring and analysis tools you already use.

    In this post, you will learn how Shield Advanced attack flow logs capture metadata during DDoS events, what each field in a flow log entry means, and how to enable and configure flow logging for your protected resources.

    How DDoS attacks affect your applications

    A DDoS attack floods an application with traffic, making it unavailable to users. Infrastructure-layer attacks saturate bandwidth and exhaust connection tables—you see packet loss and timeouts.

    Shield Advanced is a managed DDoS protection service that detects and mitigates attacks for Amazon CloudFront distributions, Elastic Load Balancing load balancers, Amazon Route 53 hosted zones, AWS Global Accelerator standard accelerators, and Elastic IP (EIP) addresses. See the AWS Shield Advanced documentation for full coverage details. Initially, Shield Advanced will provide infrastructure-layer attack flow logs for EIP protections, with support for additional resource types to follow.

    Key benefits

    Flow logs help you understand attacks in several ways:

    • Reconstruct traffic patterns – Query logs after an attack to analyze volume, source distribution, and protocol mix without relying only on aggregate CloudWatch metrics.
    • Identify attack origins – The srccountry and location fields show where traffic originated and which AWS edge location it entered.
    • Verify mitigation behavior – The action field records what Shield did with each flow.

    Logs go to Amazon S3, CloudWatch Logs, or Data Firehose. You can then query them with Amazon Athena (a serverless query service for analyzing data in Amazon S3), route them to third-party Security Information and Event Management (SIEM) platforms or build CloudWatch Logs Insights queries (an interactive log analysis feature) without deploying new infrastructure.

    What attack flow logs capture

    Log records capture source and destination IP addresses and ports, protocol, packet and byte counts, the action Shield Advanced took, and TCP flags. They also include the AWS ingress location where traffic entered and a two-letter country code for the traffic source when available. Logs are written at 5-minute intervals and are available during an active attack and after it concludes.

    The maximum file size is 75 MB. If a file reaches that limit within the 5-minute window, the file will be closed, published, and a new file will start. Flow logs support JSON, plain text, W3C, and Parquet output formats and contain the following fields:

    Field Description
    protection_arn Amazon Resource Name (ARN) of the Shield protection
    event_timestamp Timestamp of log generation
    version Flow log version number
    srcaddr Source IP address
    dstaddr Destination IP address
    srcport Source port
    dstport Destination port
    protocol IP protocol number
    packets Packet count within the aggregation window
    bytes Byte count within the aggregation window
    starttime Aggregation window start time
    endtime Aggregation window end time
    action Action taken by Shield
    location AWS ingress location
    sampling_rate Sampling rate used during packet processing
    tcp_flags TCP flags from the packet
    srccountry Two-letter country code for the traffic source

    How to configure flow logs for Shield Advanced protected resources

    The following steps walk you through creating the CloudWatch Logs delivery resources that connect a Shield Advanced protection to your preferred log destination.

    Prerequisites

    Before configuring flow logs, make sure you have:

    Flow logs incur standard CloudWatch Logs vended log charges, and the destination resources (S3 bucket storage, CloudWatch Logs log group storage, or Firehose data processing) incur separate charges. Review the Vended Logs entry on the CloudWatch pricing page and the pricing for your chosen destination service before enabling flow logs on high-traffic resources.

    How it works

    Log delivery requires three objects:

    • DeliverySource – Represents the Shield Advanced protection that produces the logs
    • DeliveryDestination – Represents where logs should be sent (Amazon S3, CloudWatch Logs, or Amazon Data Firehose)
    • Delivery – Connects the source to the destination

    This three-object model lets you reuse destinations across multiple sources and manage delivery pipelines independently. For example, you can send logs from multiple Shield protections to the same S3 bucket by creating multiple DeliverySource objects that reference the same DeliveryDestination.

    Because Shield Advanced attack flow logs use the CloudWatch Logs delivery infrastructure, you can aggregate them across accounts and Regions just like other vended logs. Deliver directly to a centralized S3 bucket with a cross-account policy, replicate CloudWatch Logs log groups using cross-account cross-Region centralization rules, or stream to a shared Firehose stream using cross-account subscriptions. Explore these options to build a unified view of DDoS attack traffic across your multi-account, multi-Region footprint.

    Step 1: Create your destination resource

    Choose a destination:

    Step 2: Configure the destination resource policy (if needed)

    The destination resource needs a policy that grants the CloudWatch Logs delivery service write permissions. The policy varies by destination type. For more information, see Logs sent to Amazon S3, Logs sent to CloudWatch Logs, or Logs sent to Firehose.

    For Amazon S3 destinations, you have two options:

    • Automatic policy creation: If your bucket has no existing resource policy and you have the s3:GetBucketPolicy and s3:PutBucketPolicy permissions, AWS automatically creates the required policy when you create the delivery in step 6. You can skip to step 3.
    • Manual policy update: If you need to customize the policy or your organization requires pre-approved policies, create the policy manually by following the instructions for Logs sent to Amazon S3.

    Step 3: Get your protection ARN

    Shield Advanced is a global service and uses the us-east-1 AWS Region for management. Run the following command to list your Shield Advanced protections.

    aws shield list-protections \
      --region us-east-1

    In the output, copy the ProtectionArn value for the protection you want to log.

    Step 4: Create a delivery source

    Run the following command to create the delivery source, replace <protection-arn> with the ProtectionArn value from step 3.

    aws logs put-delivery-source \
      --name my-shield-delivery-source \
      --resource-arn <protection-arn> \
      --log-type FLOW_LOGS \
      --region us-east-1
    

    The --resource-arn is the ARN of your Shield Advanced protection—not the protected resource itself. Shield Advanced creates a separate protection object that wraps your resource, and flow logs are generated by that protection layer rather than the underlying resource.

    Step 5: Create a delivery destination

    Run the following command to create the delivery destination, replace <resource-arn> with the ARN of the destination resource you created in step 1.

    aws logs put-delivery-destination \
      --name my-shield-delivery-destination \
      --output-format plain \
      --delivery-destination-configuration '{"destinationResourceArn":"<resource-arn>"}' \
      --region us-east-1
    

    The --delivery-destination-configuration parameter takes a JSON object with a destinationResourceArn key whose value is the ARN of your S3 bucket, log group, or Firehose stream.

    In the output, copy the value of the top-level ARN field—this is the delivery destination ARN (different from the bucket ARN). You will use this in step 6.

    Step 6: Create the delivery

    Run the following command to connect the delivery source to the delivery destination, replace <delivery-destination-arn> with the delivery destination ARN from step 5.

    aws logs create-delivery \
      --delivery-source-name my-shield-delivery-source \
      --delivery-destination-arn <delivery-destination-arn> \
      --region us-east-1
    

    Step 7: Verify the delivery

    Run the following command to confirm the delivery is active.

    aws logs describe-deliveries \
      --region us-east-1

    After delivery is active, Shield Advanced publishes flow log records to your destination during DDoS events.

    Clean up

    To avoid ongoing charges, delete the resources you created.

    1. Delete the delivery:
      aws logs delete-delivery \
        --id <delivery-id> \
        --region us-east-1

    2. Delete the delivery source:
      aws logs delete-delivery-source \
        --name my-shield-delivery-source \
        --region us-east-1

    3. Delete the delivery destination:
      aws logs delete-delivery-destination \
        --name my-shield-delivery-destination \
        --region us-east-1

    4. (Optional) Back up flow log data if you need to retain logs for compliance or analysis.
    5. Delete the destination resource. Warning: Deleting the destination resource will permanently delete all flow log data.

      For an S3 bucket:

      aws s3 rb s3://<bucket-name> \
        --force \
        --region <region>

      For a CloudWatch Logs log group:

      aws logs delete-log-group \
        --log-group-name <log-group-name> \
        --region <region>

      For a Firehose stream:

      aws firehose delete-delivery-stream \
        --delivery-stream-name <stream-name> \
        --region <region>

    Conclusion

    Shield Advanced attack flow logs provide the visibility you need to understand and respond to DDoS attacks effectively. By integrating with your existing observability infrastructure, they deliver actionable insights without requiring new tooling or complex setup. Enable flow logs on your Shield Advanced protections today to gain immediate visibility into attack patterns and strengthen your DDoS defense posture.

    Next steps:

    For the full reference about flow log configuration, see the AWS Shield Advanced documentation.

    If you have feedback about this post, submit comments in the Comments section below.


    Ken Kitts

    Ken Kitts

    Ken is a Technical Account Manager at Amazon Web Services (AWS) with over 20 years of experience in computer networking, including software-defined networking in the financial technology sector. Outside of work, Ken is an avid traveler who enjoys exploring archaeological sites and museums, with Teotihuacan in Mexico as a favorite.

    Customize federated sign-in with new Amazon Cognito Lambda trigger

    Post Syndicated from Abrom Douglas original https://aws.amazon.com/blogs/security/customize-federated-sign-in-with-new-amazon-cognito-lambda-trigger/

    You can use Amazon Cognito user pools to add sign-up and sign-in functionality to your web and mobile applications. You can authenticate users directly with Amazon Cognito managed accounts using passwords, passwordless flows, or custom authentication flows, or let users federate in through external identity providers (IdP) using SAML, OpenID Connect, or social providers such as Google, Facebook, Sign in with Apple, or Login with Amazon. For consumers, identity federation means fewer passwords to remember and a smoother sign-in experience. For business-to-business (B2B) software as a service (SaaS) providers, it means your tenants’ organizations keep control of their own identities rather than managing credentials on their behalf. But federation can also introduce challenges for enterprises and application developers. What happens when your enterprise customer’s SAML provider sends hundreds of group memberships that exceed attribute size limits? Or when your ecommerce customer forgets they already have an account and tries to sign in with a different social provider, creating duplicate records?

    In this blog post, I introduce the inbound federation Lambda trigger for Amazon Cognito, a new feature that gives you programmatic control over federated authentication flows. This AWS Lambda trigger intercepts the federated authentication response immediately after your external identity provider responds to Cognito, so you can transform, filter, and enrich user attributes before the user profile is created and user attributes are mapped in your user pool.

    Understanding the inbound federation Lambda trigger

    The inbound federation Lambda trigger is invoked after your Amazon Cognito user pool has received and verified the response from the external IdP. The request payload for the federated IdP response is then sent from Cognito to your Lambda function and you will receive the following information:

    • The common parameters of Amazon Cognito Lambda triggers (including userPoolId and clientId)
    • Which external IdP was used (for example, providerName)
    • The providerType (SAML, OIDC, Login with Amazon, and so on)
    • Attribute data from the external IdP specific to the user signing in

    The specific format of this attribute data depends on the provider type, view the Inbound federation Lambda trigger parameters section in the docs to learn more. If the external IdP is a SAML provider, you will receive a JSON key-pair listing of the user’s attributes from the IdP assertion. If the external IdP is an OIDC provider (or social provider), you will receive the access token and attribute data from the /userinfo endpoint, along with an ID token if one was provided. See Figure 1 for a detailed flow of a federated sign-in with an Amazon Cognito user pool configured to use the inbound federation Lambda trigger.

    Figure 1: Sequence flow of a federated login configured with the inbound federation Lambda trigger

    Figure 1: Sequence flow of a federated login configured with the inbound federation Lambda trigger

    1. The user begins using the application but is required to sign in first.
    2. The managed login is rendered, and the user can select which IdP they want to sign in with. If identifiers are used with SAML or OIDC providers, the user enters their email address and Amazon Cognito looks up the domain of their provided email and routes them to the appropriate IdP.
    3. Alternatively, the managed login can be bypassed by the client providing the identity_provider request parameter.
    4. Amazon Cognito sends the authentication request to the appropriate IdP.
    5. The external IdP challenges the user to sign in.
    6. The user completes the sign-in process required by the external identity provider.
    7. The challenge response is sent to the external IdP.
    8. The IdP verifies that the sign-in is successful. If there are any subsequent challenges, such as multi-factor authentication (MFA), additional rounds of authentication challenges and responses take place. This is determined by the configuration and settings of the external IdP.
    9. The external IdP sends a response to the Amazon Cognito user pool, and Cognito validates the cryptographic signature and that it hasn’t been tampered with.
    10. Amazon Cognito sends attribute data from the IdP to the inbound federation Lambda function
    11. Attribute data for the authenticated user and the common parameters for Amazon Cognito are available for the Lambda function to add, modify, or suppress according to your requirements.
    12. Your added, modified, or suppressed attributes are returned to Amazon Cognito. These are attribute values that map to the user’s profile in Cognito—whether the user profile was just created or is being updated for a returning user.
    13. Continuing the OAuth 2.0 authorization code grant, Amazon Cognito sends an authorization code to the client.
    14. The client then calls the /token endpoint with the authorization code.
      Note: It’s a security best practice to use confidential clients and to use OAuth 2.0 Proof Key for Code Exchange (PKCE) extension whenever possible.
    15. An access, ID, and refresh token is returned to the client.
    16. The user has signed into the application. ID tokens can be used to identify who the user is (authentication), and access tokens can be used to determine what the user can do (authorization).

    Common federation challenges and use cases

    Federation introduces complexity that varies depending on your use case. For B2B and SaaS applications, you’re often not in control of your customers’ IdPs, including what attributes they send or how they format them. As an example, an enterprise customer will configure their SAML response to include every group a user belongs to. This could be hundreds of groups or long group identifiers, and if the group membership of the user is mapped to an Amazon Cognito attribute, this can lead to a scenario where the Cognito attribute size limit is exceeded, causing federated sign-ins to fail.

    Challenges for business-to-customer (B2C) applications can differ from B2B use cases. For B2C applications, organizations shouldn’t be required to think about identity providers. The ability to sign-up and sign-in should be seamless for consumer-facing applications. Customers visiting a consumer-facing application might create an account with email and password, forget they created created it, and then later try signing in with Facebook (or other social provider). Without proper account linking in Amazon Cognito, you then have multiple user records for the same user, which could lead to fragmented purchase history and a frustrating customer experience.

    Both B2B and B2C use cases might need to look up external data just prior to completing the sign-in process, such as additional roles and access for B2B users or looking up active orders for B2C users. Another example could be the need to normalize data just prior to storing it in the user profile within the Amazon Cognito user pool or even discarding personally identifiable information (PII) prior to storing it in your Cognito user pool.

    With the inbound federation Lambda trigger, you can handle these B2B and B2C use cases programmatically, and do so without requiring modification of your applications or coordinating IdP-specific changes with external IdPs. In this section, I dive deeper into two common use cases: oversized group attributes, common with B2B customers, and automated account linking, common with B2C customers.

    Use case 1: Filtering oversized group attributes

    If you have B2B and SaaS use cases, it’s a common practice to use group membership from the IdP to determine the level of access you have within the SaaS service. This is a great way to still provide some access control back to the enterprise customers themselves. The groups can be used to represent the roles a user will have or for some form of coarse-grained authorization. However, your customers might inadvertently send a large number of groups a user is a member of, thus leading to an oversized attribute payload.

    Another common scenario is where the syntax and format of group name a user belongs to can arrive in various formats across different IdPs; such as a canonical name (for example, example.com/groups/myApp-readOnly), a distinguished name (common with LDAP based systems and such as cn=myApp-readOnly,OU=groups,DC=example,DC=com), or a plain text string (such as myApp-readOnly). Instead of having downstream authorization logic to accommodate different variations of a group name, you can now normalize how groups are represented prior to storing the user’s attribute data using the inbound federation Lambda trigger.

    To expand this, imagine your enterprise customer uses a SAML IdP, such as Active Directory Federation Services (AD FS), in front of Active Directory (AD). When their users authenticate, AD FS sends a groups attribute containing every AD group the user belongs to. For users in large organizations, this can be hundreds of groups, and the attribute is mapped to an Amazon Cognito attribute, this could result in a string that exceeds 2,048-character limit per attribute of Cognito. Authentication would fail in this scenario, ultimately leading to support tickets because enterprise customers would be unable to sign in. Even if certain users didn’t exceed this limit, because of a smaller number of group memberships, this would result in the collection and storing of unnecessary data in your Cognito user pool.

    Previously, you would need to work with your customer’s IT department to modify their SAML configuration to filter groups at the source—a process that could take weeks and require multiple approval cycles because it involves a change to the federation configuration. Especially for SaaS customers, this isn’t a scalable approach because you could integrate with hundreds of external IdPs. With the inbound federation Lambda trigger, you can solve this by filtering the groups to only those relevant to your application and normalizing the nomenclature of these groups. The following Lambda function filters the groups attribute to include only groups relevant to your application and normalizes the names of groups.

    // Configure the group prefix to filter on (e.g. "App1-", "myApp-", etc.)
    // Change this to match the prefix your IdP uses for relevant group names.
    const GROUP_PREFIX = process.env.GROUP_PREFIX || 'myApp-';
    
    // The SAML attribute/claim name that contains group membership.
    // Common values: "groups", "memberOf", "http://schemas.xmlsoap.org/claims/Group", etc.
    const GROUP_ATTRIBUTE = process.env.GROUP_ATTRIBUTE || 'groups';
    
    /**
     * Extracts the short group name from common IdP formats:
     *   - Plain text:       "myApp-readOnly"
     *   - Leading slash:    "/myApp-readOnly"
     *   - Canonical/URL:    "example.com/groups/myApp-readOnly"
     *   - Distinguished name (DN): "cn=myApp-readOnly,OU=groups,DC=example,DC=com"
     * Returns the last meaningful segment so all formats normalize to "myApp-readOnly".
     */
    
    function extractGroupName(raw) {
      let name = raw.trim();
    
      // Some IdPs prefix group names with "/" to indicate a top level group — strip it before format detection
      if (name.startsWith('/')) {
        name = name.substring(1);
      }
    
      // DN format — extract the CN (common name) value
      if (/^cn=/i.test(name) || /,\s*(ou|dc)=/i.test(name)) {
        const cnMatch = name.match(/^cn=([^,]+)/i);
        return cnMatch ? cnMatch[1].trim() : name;
      }
    
      // URL / path format — take the last segment after the final "/"
      if (name.includes('/')) {
        const segments = name.split('/').filter(Boolean);
        return segments[segments.length - 1];
      }
    
      return name;
    }
    export const handler = async (event) => {
      try {
        console.log('Full event:', JSON.stringify(event, null, 2));
        console.log('Provider type:', event.request?.providerType);
    
        // Initialize the response structure
        event.response = event.response || {};
    
        if (event.request?.providerType?.toLowerCase() === "saml") {
          const samlResponse = event.request.attributes?.samlResponse;
    
          if (samlResponse) {
            console.log('Original SAML Attributes:', JSON.stringify(samlResponse, null, 2));
    
            // Build the attribute map — you MUST include every attribute you want Cognito to retain. Anything omitted from userAttributesToMap is dropped.
            const mappedAttributes = {};
    
            Object.keys(samlResponse).forEach(key => {
              if (key === GROUP_ATTRIBUTE) {
                // Parse the groups JSON string from the SAML assertion
                let groupsArray = [];
                try {
                  groupsArray = JSON.parse(samlResponse[GROUP_ATTRIBUTE]);
                } catch (error) {
                  console.error(`Error parsing ${GROUP_ATTRIBUTE}:`, error);
                }
    
                // Normalize each group name, then filter to the configured prefix
                const normalizedGroups = groupsArray.map(extractGroupName);
                const filteredGroups = normalizedGroups.filter(group =>
                  group.startsWith(GROUP_PREFIX)
                );
    
                console.log(`Original ${GROUP_ATTRIBUTE}:`, groupsArray);
                console.log(`Normalized ${GROUP_ATTRIBUTE}:`, normalizedGroups);
                console.log(`Filtered ${GROUP_ATTRIBUTE}:`, filteredGroups);
    
                // Only include the groups attribute if there are matching groups
                if (filteredGroups.length > 0) {
                  mappedAttributes[GROUP_ATTRIBUTE] = filteredGroups.map(group => `'${group}'`).join(', ');
                }
              } else {
                // Pass all other SAML attributes through unchanged
                mappedAttributes[key] = samlResponse[key];
              }
            });
    
            event.response.userAttributesToMap = mappedAttributes;
            console.log('Response to Cognito:', JSON.stringify(event.response, null, 2));
          }
        }
    
        // For any unhandled provider type (or missing samlResponse), this intentionally does NOT set userAttributesToMap and tells Cognito to keep all original IdP attributes unchanged (no-op).
    
        // To handle OIDC or social providers, add additional logic here using event.request.attributes.idToken, .userInfo, and/or .tokenResponse.
    
        return event;
      } catch (error) {
        console.error('Error in Lambda:', error);
        throw error;
      }
    };
    

    This approach reduces a large group list to only what is applicable to your application. Authentication succeeds, and you maintain control over your user pool’s data without depending on external configuration changes.

    Use case 2: Automatic account linking

    The second use case addresses a challenge that’s particularly common in B2C facing ecommerce or any consumer-facing applications; although it can also be applicable to B2B scenarios. Imagine you’re running an online retail store. A customer creates an account with their email and password to make a purchase. A few months later, they return to your site but forgot they already created an account and they see the Login with Amazon button and decide to sign in this way. Without account linking, Amazon Cognito creates a new federated user because these are technically distinct accounts, and now this customer has two separate accounts with different purchase histories and saved preferences.

    This fragmentation creates a poor customer experience and complicates your business operations. You can’t see the customer’s complete purchase history, loyalty points are split across accounts, and your analytics show two distinct customers instead of one.

    The inbound federation Lambda trigger can be used to solve this by automatically linking federated identities to existing local accounts based on email address. While account linking can also be implemented in a pre-sign-up Lambda trigger, the inbound federation trigger runs on every federated sign-in, not just the first, giving you access to the latest IdP attributes and the ability to apply linking logic continuously rather than only at initial account creation. If no local Amazon Cognito account exists, you can create one and then link the social provider account to it. The local account can serve as the primary identity, ensuring consistent JSON Web Tokens (JWTs) regardless of how the user signs in. The following is an example of an inbound federation Lambda trigger that can help address this use case.

    import { 
      CognitoIdentityProviderClient, 
      ListUsersCommand,
      AdminCreateUserCommand,
      AdminLinkProviderForUserCommand
    } from "@aws-sdk/client-cognito-identity-provider";
    
    const client = new CognitoIdentityProviderClient();
    
    export const handler = async (event) => {
      try {
        console.log('Full event:', JSON.stringify(event, null, 2));
        
        const { userPoolId, request, userName } = event;
        const { providerName, providerType, attributes } = request;
        
        // Extract email and profile attributes based on provider type
        const { email, givenName, surname } = extractAttributes(providerType, attributes);
        
        if (!email) {
          console.error('No email found in federated response');
          return event;
        }
        
        console.log(`Processing federated login for email: ${email}, provider: ${providerName} (${providerType})`);
        
        // Check if a local user exists with this email
        const existingUser = await findLocalUserByEmail(userPoolId, email);
        
        if (existingUser) {
          console.log(`Found existing local user: ${existingUser.Username}`);
          if (isAlreadyLinked(existingUser, providerName, userName)) {
            console.log(`Federated identity ${providerName}:${userName} is already linked to ${existingUser.Username}, skipping link`);
          } else {
            await linkFederatedUser(userPoolId, existingUser.Username, providerName, userName);
          }
        } else {
          console.log('No existing local user found, creating new one');
          const newUsername = await createLocalUser(userPoolId, email, givenName, surname);
          await linkFederatedUser(userPoolId, newUsername, providerName, userName);
        }
        
        return event;
        
      } catch (error) {
        console.error('Error in account linking Lambda:', error);
        throw error;
      }
    };
    
    
    /**
     * Check if the federated identity is already linked to the local user by inspecting the identities attribute from the ListUsers response.
     */
    function isAlreadyLinked(user, providerName, federatedUsername) {
      const identities = user.Attributes?.find(a => a.Name === 'identities');
      if (!identities?.Value) return false;
    
      try {
        const parsed = JSON.parse(identities.Value);
        return parsed.some(id => id.providerName === providerName && id.userId === federatedUsername);
      } catch {
        return false;
      }
    }
    
    /**
     * Extract email and profile attributes based on provider type.
     * - SAML: attributes come from samlResponse
     * - OIDC/Social: attributes come from userInfo, falling back to idToken (if one exists)
     */
    function extractAttributes(providerType, attributes) {
      if (providerType?.toLowerCase() === 'saml') {
        const saml = attributes?.samlResponse;
        return {
          email: saml?.email || null,
          givenName: saml?.givenName || '',
          surname: saml?.surname || ''
        };
      }
    
      // OIDC and social providers: prefer userInfo, fall back to idToken
      const userInfo = attributes?.userInfo;
      const idToken = attributes?.idToken;
    
      const source = userInfo?.email ? userInfo : idToken;
    
      return {
        email: source?.email || null,
        givenName: source?.given_name || '',
        surname: source?.family_name || ''
      };
    }
    
    /**
     * Find a local Cognito user (not EXTERNAL_PROVIDER) by email address.
     */
    async function findLocalUserByEmail(userPoolId, email) {
      try {
        const command = new ListUsersCommand({
          UserPoolId: userPoolId,
          Filter: `email = "${email}"`
        });
        
        const response = await client.send(command);
        console.log('ListUsers response:', JSON.stringify(response, null, 2));
        
        if (!response.Users || response.Users.length === 0) {
          return null;
        }
    
        // Find the first user that is a true local account (not a federated-only profile)
        const localUser = response.Users.find(u => u.UserStatus !== 'EXTERNAL_PROVIDER');
        return localUser || null;
      } catch (error) {
        console.error('Error finding user by email:', error);
        throw error;
      }
    }
    
    /**
     * Create a new local Cognito user without a password.
     * With passwordless (email OTP) enabled on the user pool, the user is created with UserStatus=CONFIRMED and no FORCE_CHANGE_PASSWORD state.
     */
    async function createLocalUser(userPoolId, email, givenName, surname) {
      try {
        const userAttributes = [
          { Name: 'email', Value: email }
        ];
    
        if (givenName) userAttributes.push({ Name: 'given_name', Value: givenName });
        if (surname) userAttributes.push({ Name: 'family_name', Value: surname });
    
        const command = new AdminCreateUserCommand({
          UserPoolId: userPoolId,
          Username: email,
          UserAttributes: userAttributes,
          MessageAction: 'SUPPRESS'
        });
        
        const response = await client.send(command);
        console.log(`Created local user: ${email}`, JSON.stringify(response, null, 2));
        
        return email;
      } catch (error) {
        console.error('Error creating local user:', error);
        throw error;
      }
    }
    
    /**
     * Link a federated user identity to a local Cognito user.
     * The local user becomes the primary profile — all future JWTs will represent this local user regardless of sign-in method.
     */
    async function linkFederatedUser(userPoolId, localUsername, providerName, federatedUsername) {
      try {
        const command = new AdminLinkProviderForUserCommand({
          UserPoolId: userPoolId,
          DestinationUser: {
            ProviderName: 'Cognito',
            ProviderAttributeValue: localUsername
          },
          SourceUser: {
            ProviderName: providerName,
            ProviderAttributeName: 'Cognito_Subject',
            ProviderAttributeValue: federatedUsername
          }
        });
        
        const response = await client.send(command);
        console.log(`Linked federated user ${federatedUsername} to local user ${localUsername}`);
        console.log('Link response:', JSON.stringify(response, null, 2));
        
        return response;
      } catch (error) {
        if (error.name === 'AliasExistsException' || error.message?.includes('already linked')) {
          console.log(`User already linked: ${error.message}`);
          return;
        }
        console.error('Error linking federated user:', error);
        throw error;
      }
    }
    

    Every federated sign-in will invoke the inbound federation Lambda trigger, and the logic is straightforward. When a user authenticates with an external identity provider, the trigger extracts their email from the federated response and searches the user pool for a local Cognito account with that same email. If one exists—such as if the user originally signed up with email and password—the Lambda function links the federated identity to that existing local account. If no local account exists, the trigger creates one on the fly as a passwordless account (confirmed, suppressing any emails, and ready for passwordless email one-time passcode (OTP) sign-in), then links the federated identity to it. In both cases, the local account is set as the primary profile. This means the user’s JWTs always carry the same sub-claim regardless of how they sign in—directly, or through Google, Facebook, or SAML—your application sees one consistent identity. The preceding Lambda trigger is also smart enough to check whether a linked account already exists before making the call, so returning users who’ve already been linked don’t generate unnecessary API calls. And because the local account supports passwordless authentication, a user who first arrived through federation can later sign in directly with an emailed OTP—or even add a password later through your applications account settings. The local account is always the anchor.

    Best practices

    As you implement these patterns, keep a few best practices in mind. Your Lambda function must be completed within 5 seconds, so optimize for speed to help ensure the federated sign-in process is able to successfully complete. If you’re making external calls within the inbound federation Lambda function, like Amazon DynamoDB queries or API requests, implement caching where possible. Handle errors gracefully—if your Lambda function throws an exception or an error, authentication could fail for the user. Consider logging the error and returning the original event back to Amazon Cognito rather than failing authentication for a legitimate user attempting to sign in. Here are some additional best practices for working with Lambda functions.

    For the account linking use case, automatic linking relies on matching the email from the federated identity to a local account. However, there are scenarios where this match won’t exist. For example, Apple’s Hide My Email feature generates a unique alias for each app, so the federated email won’t match any existing local account. This is an effective privacy feature but it also blocks the ability to automatically link accounts. In cases like these, your application will need to implement a user-initiated account linking flow, such as prompting the user to verify ownership of both email addresses before calling the AdminLinkProviderForUser API to complete the link.

    Monitor your Lambda function performance using Amazon CloudWatch metrics. Set up alarms for errors, timeouts, and throttling so you can respond quickly if issues arise. I also recommend capturing sample event payloads from a CloudWatch log group during your initial development and deployment—these will be valuable for local testing and debugging which can lead to quicker resolution if issues arise in your production environment. This is especially important as different IdPs (namely SAML and OIDC providers) may respond with varying attribute and value syntaxes. Consider implementing CloudWatch alarms to alert your security and operational teams if authentication failures spike, which could indicate an attempted attack, misconfiguration, or provide insight into further optimization of your inbound federation Lambda trigger.

    Conclusion

    In this post, you learned about the new inbound federation Lambda trigger for Amazon Cognito and how it can solve various use cases. You walked through two common federation challenges and reviewed some sample code to help resolve those challenges. For B2B and SaaS applications, the inbound federation Lambda trigger gives you control when dealing with oversized attributes from external identity providers (such as group membership) without requiring coordination with enterprise IT teams. For B2C and consumer-facing applications, it enables seamless account linking across multiple authentication methods, creating a unified customer experience.

    The new Lambda trigger works with SAML, OIDC, and supported social providers, and is available now in AWS Regions where Amazon Cognito is available. To learn more about the new Lambda trigger and others, see the Amazon Cognito Developer Guide.

    What federation challenges are you facing in your applications? I’d love to hear about your use cases in the comments below and over at AWS re:Post.

    Abrom-Douglas-author

    Abrom Douglas

    Abrom is a Senior Solutions Architect within AWS Identity with over 20 years of software engineering and security experience, specializing in the identity and access management space. He loves speaking with customers about how identity and access management can provide secure outcomes that enable both business and technology initiatives. In his free time, he enjoys cheering for Arsenal FC, photography, travel, volunteering, and competing in duathlons.

    Identify unused AWS KMS keys and prevent accidental key deletions

    Post Syndicated from Andrea Rossi original https://aws.amazon.com/blogs/security/identify-unused-aws-kms-keys-and-prevent-accidental-key-deletions/

    As you scale your use of Amazon Web Services (AWS), managing KMS keys becomes increasingly important. Whether you manage a handful of keys or thousands across multiple AWS accounts and AWS Regions, there’s often a need to audit key usage to help you meet compliance requirements, evaluate your risk posture, and optimize key management costs. However, determining which keys are actively in use and which have been sitting idle can be a time consuming and complex task.

    To help with this, AWS Key Management Service (AWS KMS) has launched the GetKeyLastUsage API, a new feature that you can use to quickly determine when each key was last used for a cryptographic operation, significantly enhancing your audit capabilities and key lifecycle management. For more information, see Determine past usage of a KMS key.

    Before this launch, the primary way to audit key usage was through AWS CloudTrail logs. CloudTrail captures every cryptographic operation by default, so the data is available. The difficulty is turning that data into actionable insight. You need to identify which keys to examine, query the right logs, and repeat that process frequently enough to maintain an accurate view. For the most recent 90 days, CloudTrail event history makes this manageable. Beyond that, you need to create a dedicated trail to deliver logs to Amazon Simple Storage Service (Amazon S3) for long-term retention, then query those logs using tools such as Amazon Athena to determine when a key was last used.

    Determine when a key was last used

    AWS KMS now provides a direct way to see when a key was last used for cryptographic operations. You can also see this information using the AWS Management Console for AWS KMS and the AWS Command Line Interface (AWS CLI).

    The GetKeyLastUsage API returns the date and time of the most recent cryptographic operation performed with a KMS key, without requiring you to search through CloudTrail logs. The API returns the date and time of the last key operation, the type of operation performed, CloudTrail event ID, and KMS request ID. You can access this information for all customer-managed keys and AWS managed keys irrespective of key spec, key origin, key store, or key usage type.

    In addition, you can restrict a key from being disabled or scheduled for deletion if it was recently used, by incorporating this usage information as a condition within the KMS key policy. See the Preventing accidental key deletion with policy controls section for implementation details.

    About the tracking period

    One of the important concepts you must understand before relying on the last usage information reported on a KMS key is the tracking period. The tracking period is the date from which AWS KMS began tracking cryptographic activity for the key. Tracking began on April 23, 2026, for most AWS Regions. Understanding the tracking period is critical because it determines whether the absence of usage information means a key has never been used or only hasn’t been used since tracking started.

    For example, if you have a key created on January 1, 2026, and you check its usage, any cryptographic operations that occurred between January 1 and April 22 wouldn’t be captured in the usage information. Thus, you can’t conclude that it’s never been used, because it might have been used in the months before tracking began.

    Getting started

    There’s nothing to enable or additional configuration required to view usage information on last cryptographic operation performed on your KMS keys.

    To view KMS key usage:

    1. Go to the AWS KMS console and choose Customer-managed keys in the navigation pane and select a key. Look for Last used on the general configuration.
      Figure 1: KMS key general configuration page

      Figure 1: KMS key general configuration page

    2. Choose the link under Last used to see additional details such as Timestamp, Operation, and the CloudTrail event ID.
      Figure 2: View last used details including timestamp, operation, and event ID

      Figure 2: View last used details including timestamp, operation, and event ID

    3. The Last used column is also shown when you attempt to schedule key deletion, so that you can make informed decisions.
      Figure 3: Scheduled key deletion warning

      Figure 3: Scheduled key deletion warning

    API reference

    See the following examples for ideas on how to use the GetKeyLastUsage API to better understand KMS key usage.

    Use case 1: Cost optimization through unused key cleanup

    If you manage thousands of AWS KMS keys distributed across multiple AWS accounts, you might have keys that have remained unused since creation or keys that are no longer needed. By cleaning up these keys, you can reduce operational costs and minimize your security footprint. However, without visibility into which keys are actively performing cryptographic operations, it can be difficult to distinguish between keys protecting critical workloads and those that can be safely decommissioned.

    Note that there are some precautions that you should take before scheduling key deletion. While the last usage information can help identify unused keys, it shouldn’t be the only factor in deciding whether to delete or disable a key. The last usage information tells you when a key was last used, not whether it will be needed in the future. A key might be unused for months but still required to decrypt files, for compliance scenarios or disaster recovery as shown in figure 4.

    When you identify a potentially unused key, first disable it using DisableKey and monitor your applications and services for any encryption or decryption failures.

    Figure 4: A use case where GetKeyLastUsage doesn’t accurately reflect whether a KMS key is still required

    Figure 4: A use case where GetKeyLastUsage doesn’t accurately reflect whether a KMS key is still required

    As an example, Amazon EBS volumes only interact with KMS keys during specific lifecycle events like volume creation, attachment, and detachment. After a volume is attached to an Amazon Elastic Compute Cloud (Amazon EC2) instance, the plaintext data encryption key is cached in the Nitro Card hardware, and all subsequent read/write operations use this cached key without any further AWS KMS API calls. This means a production volume running continuously for months or years will show no KMS activity during that entire period. However, the volume remains completely dependent on that KMS key for any future operations like instance restarts, volume reattachments, or disaster recovery scenarios. If someone deletes the KMS key, the encrypted data key stored with the volume can never be decrypted again, making the volume’s data permanently and irreversibly inaccessible. Before deleting any KMS key, you must verify it has no associated EBS volumes or snapshots, regardless of how long ago the last KMS API call occurred.

    AWS provides a mechanism where you can create a CloudWatch alarm that notifies you if a key pending deletion is being accessed, giving you an opportunity to cancel the deletion before data becomes inaccessible.

    Solution with GetKeyLastUsage API

    Here’s a sample script that scans all customer-managed keys in an account and retrieves each key’s last usage date through the GetKeyLastUsage API. It accepts two optional inputs: a threshold in days and an AWS Region. The script filters and displays only keys that haven’t been used within the specified period, presenting results in a table with the key name, AWS account ID, AWS Region, and last usage date. This can help you identify unused encryption keys.

    The following is an example to scan all keys that haven’t been used in the last 180 days in the us-east-1 Region:

    ./script.sh 180 us-east-1
    #!/bin/bash
    DAYS=${1:-90}
    REGION=${2:-$(aws configure get region)}
    CUTOFF=$(date -v-${DAYS}d +%s 2>/dev/null || date -d "-${DAYS} days" +%s)
    ACCOUNT_ID=$(aws sts get-caller-identity --query Account --output text)
    printf "Showing keys not used in the last %s days (Region: %s)\n\n" "$DAYS" "$REGION"
    printf "%-50s %-15s %-20s %-15s\n" "Key Name" "Account ID" "Region" "Last Usage Date"
    printf "%.0s-" {1..100}
    printf "\n"
    for key_id in $(aws kms list-keys --region $REGION --query 'Keys[*].KeyId' --output text); do
    key_manager=$(aws kms describe-key --region $REGION --key-id $key_id --query 'KeyMetadata.KeyManager' --output text)
    if [ "$key_manager" = "CUSTOMER" ]; then
    last_usage=$(aws kms get-key-last-usage --region $REGION --key-id $key_id)
    timestamp=$(echo $last_usage | jq -r '.KeyLastUsage.TimeStamp // empty')
    if [ -z "$timestamp" ]; then
    last_epoch=0
    else
    last_epoch=$(date -jf "%Y-%m-%dT%H:%M:%S" "$(echo $timestamp | cut -d. -f1)" +%s 2>/dev/null || date -d "$timestamp" +%s)
    fi
    if [ "$last_epoch" -lt "$CUTOFF" ]; then
    key_alias=$(aws kms list-aliases --region $REGION --key-id $key_id --query 'Aliases[0].AliasName' --output text)
    key_name=${key_alias:-$key_id}
    [ "$key_name" = "None" ] && key_name=$key_id
    if [ -z "$timestamp" ]; then
    tracking_date=$(echo $last_usage | jq -r '.TrackingStartDate' | cut -d'T' -f1)
    last_used="${tracking_date}*"
    else
    last_used=$(echo $timestamp | cut -d'T' -f1)
    fi
    printf "%-50s %-15s %-20s %-15s\n" "$key_name" "$ACCOUNT_ID" "$REGION" "$last_used"
    fi
    fi
    done
    printf "\n* = No operations performed since tracking started\n"

    Use case 2: Preventing accidental key deletion with policy controls

    Organizations frequently face the risk of accidental key deletions, which can have severe operational consequences. Despite precautions and safety measures, accidents can happen. A key might be deleted because someone believes it’s no longer in use, only to discover that critical applications or workloads depend on it. This results in data access failures, application downtime, and emergency recovery procedures. Without visibility into recent key usage, teams lack the information needed to make safe disable decisions or implement effective safeguards.

    Solution with policy based controls

    To prevent KMS keys from being accidentally Disabled or Deleted use the kms:TrailingDaysWithoutKeyUsage condition key in key policies to automatically block deletion or disabling of recently used keys:

    1. Open the AWS KMS console and choose Customer managed keys in the navigation pane.
    2. Select the key you want to protect.
    3. In the Key policy tab, choose Edit.
    4. In the policy editor, add the following statement:
    {
      "Sid": "PreventDeletionOfRecentlyUsedKeys",
      "Effect": "Deny",
      "Principal": "*",
      "Action": [
        "kms:ScheduleKeyDeletion",
        "kms:DisableKey"
      ],
      "Resource": "*",
      "Condition": {
        "NumericLessThanEquals": {
          "kms:TrailingDaysWithoutKeyUsage": "365"
        }
      }
    }
    1. Choose Save changes.

    The policy prevents deletion or disabling a key if it was used within the past 365 days. You can adjust the threshold to match your organization’s requirements. For more information about the condition key, see kms:TrailingDaysWithoutKeyUsage.

    Important considerations

    When reviewing key usage for possible deletion, consider the following:

    • Key deletion is irreversible and makes encrypted data unrecoverable. AWS enforces a 7–30 day waiting period. During this time, monitor usage attempts and cancel the deletion if necessary. Delete a key only if you’re certain that no data has been encrypted or will be encrypted with it. Consider disabling the key first to test the impact of unavailable keys.
    • CloudTrail remains authoritative because it provides the full audit trail. GetKeyLastUsage quickly tells you when and what operations occurred, but CloudTrail shows you who made the request and with what parameters. Learn more about logging KMS API calls with CloudTrail.

    Conclusion

    The GetKeyLastUsage API enhances your KMS key management capabilities by providing immediate access to usage data that was previously only present in CloudTrail logs. Start by opening the AWS KMS console and checking the Last used field for any customer-managed keys and AWS managed keys to see this information in action. For broader key auditing, integrate the API into your existing automation scripts using the AWS CLI examples provided.

    If you have feedback about this post, submit comments in the Comments section below.


    Andrea Rossi

    Andrea Rossi

    Andrea is the Solutions Architect who always asks “but is it secure?” one more time. Based in Milan, Italy, he works with customers to architect cloud solutions where security is foundational, not an afterthought, from network-level hardening to integrating Generative AI workloads into compliant environments.

    Poojil Tripathi

    Poojil Tripathi

    Poojil is a Solutions Architect based in Austin, TX, who would like to remind you that you should never click on links. He works with customers to design secure-by-design cloud solutions on AWS, specializing in encryption and healthy paranoia.

    Secure multi-tenant AI agents with Amazon Bedrock AgentCore resource-based policies

    Post Syndicated from Satyen Verma original https://aws.amazon.com/blogs/security/secure-multi-tenant-ai-agents-with-amazon-bedrock-agentcore-resource-based-policies/

    Software as a service (SaaS) providers building AI-powered applications on Amazon Bedrock AgentCore often need to serve multiple tenants with distinct security requirements from a shared infrastructure. Some tenants require cross-account access from their own Amazon Web Services (AWS) accounts, while others mandate that traffic stay within a private virtual private cloud (VPC) for regulatory compliance. Without centralized resource-level control, managing these diverse requirements can be complex.

    AgentCore supports resource-based policies, giving you centralized, resource-level control over who can access your AgentCore Runtime and AgentCore Runtime endpoint resources and under what conditions.

    In this post, you walk through a multi-tenant AI customer service platform where two tenants need different levels of access to the same agent. You learn how to use resource-based policies on AgentCore to grant cross-account access for one tenant while restricting another to VPC-only traffic—all while sharing the same underlying AgentCore Runtime and AgentCore Runtime endpoint.

    The multi-tenant scenario

    Imagine you’re an SaaS provider who builds and operates an AI-powered customer service platform. You use AgentCore to deploy intelligent agents that handle customer inquiries, answering product questions, processing returns, and escalating complex issues to human agents.

    You serve multiple enterprise clients (tenants), each with their own AWS account and unique security requirements:

    • Tenant A: Example Corp is a large retailer operating in AWS account 111122223333. Their development team is building a customer-facing chat agent that calls your AI agent to answer product questions in real time, and their admin team needs access to test agent behavior and monitor responses. Both roles must invoke the agent directly from Example Corp’s own AWS account without you having to share credentials or create AWS Identity and Access Management (IAM) users on their behalf. Example Corp has no network restriction requirements—their teams can invoke the agent from any network path as long as they have valid AWS credentials.
    • Tenant B: AnyCompany is a healthcare company operating in AWS account 444455556666. Because of regulatory (HIPAA) requirements, AI agent traffic must originate only from their private VPC (vpc-health1234). Their internal support staff uses the AI agent to assist with patient billing inquiries, which might involve protected health information (PHI). Their compliance team mandates that no API call to the agent can be made from developer laptops, public endpoints, or any network outside the controlled VPC boundary.
    • Your platform (SaaS provider) runs in account 555555555555 in the us-west-2 AWS Region. You operate an AgentCore Runtime (support-agent-runtime) that handles the core customer service logic, and an AgentCore Runtime endpoint (DEFAULT) that routes requests to the latest version of the support agent. Both tenants share this same agent infrastructure.

    You can use resource-based policies to define who can access your AgentCore Runtime and AgentCore Runtime endpoint directly on the resources themselves—centralizing access control on the resource side. For cross-account scenarios like Example Corp, both a resource-based policy on your resources and an identity-based policy in the tenant’s account are required. For VPC-restricted scenarios like AnyCompany, you can use specific IAM conditions to enforce that requests originate only from an approved VPC, adding a network-level security boundary on top of identity-based controls.

    Solution architecture

    The following diagram shows the architecture for the multi-tenant AI customer service platform with both access patterns.

    Figure 1: Architecture for the multi-tenant AI customer service platform with both access patterns

    Figure 1: Architecture for the multi-tenant AI customer service platform with both access patterns

    • Your account (555555555555) with AgentCore Runtime and AgentCore Runtime endpoint
    • Example Corp’s account (111122223333) with DeveloperRole and AdminRole
    • AnyCompany’s account (444455556666) with VPC boundary and ApplicationRole
    • Policy enforcement points on both resources
    • VPC endpoint in AnyCompany’s VPC connecting to AgentCore

    The SaaS provider account (555555555555) hosts the AgentCore Runtime and AgentCore Runtime endpoint that both tenants share. Example Corp (111122223333) accesses the agent cross-account using IAM roles—DeveloperRole and AdminRole—authenticated with Signature Version 4 (SigV4), the standard AWS request signing protocol. AWS evaluates both the resource-based policy on your resources and the identity-based policy in Example Corp’s account before granting access.

    AnyCompany (444455556666) also accesses the agent cross-account, but with an additional constraint: all requests must originate from within their private VPC (vpc-health1234) through a VPC endpoint for AgentCore. The resource-based policy on your resources includes an explicit Deny statement that blocks any request from AnyCompany’s ApplicationRole when it doesn’t originate from the approved VPC.

    In both cases, resource-based policies must be applied to both the AgentCore Runtime and AgentCore Runtime endpoint. AWS evaluates policies on both resources for InvokeAgentRuntime operations—if either resource denies access or lacks an explicit Allow, the request is denied.

    Prerequisites

    Before you begin, ensure you have the following:

    • An AWS account with AgentCore access and permissions to call PutResourcePolicy, GetResourcePolicy, and DeleteResourcePolicy on AgentCore resources
    • AWS Command Line Interface (AWS CLI) v2 installed and configured with the bedrock-agentcore-control API available
    • An AgentCore Runtime with SigV4 authentication and a DEFAULT AgentCore Runtime endpoint pointing to the latest runtime version

    For the VPC-restricted scenario, the tenant must have a VPC endpoint for AgentCore configured in their VPC. An interface VPC endpoint creates a private connection between the tenant’s VPC and the AgentCore service without requiring traffic to traverse the public internet. For more information, see Interface VPC endpoints for Amazon Bedrock AgentCore.

    Implementation

    Both Example Corp and AnyCompanyoperate in separate AWS accounts from your platform. For cross-account access to AgentCore Runtime, AWS requires that both of the following allow the action:

    • A resource-based policy in your platform account applied to both the AgentCore Runtime and its AgentCore Runtime endpoint. InvokeAgentRuntime operations require an explicit Allow on both resources—if either lacks one, the request is denied.
    • An identity-based policy attached to the caller’s IAM role in the tenant’s account.

    If either side is missing or denies the action, the request is denied.

    Step 1: Configure cross-account access for Example Corp (Tenant A)

    Example Corp’s DeveloperRole and AdminRole in account 111122223333 need to invoke your AI customer service agent. Without resource-based policies, enabling this cross-account access would typically require Example Corp’s roles to assume a role in your platform account through IAM role chaining—adding operational complexity, introducing temporary credential management, and creating additional IAM roles that must be maintained in your account for each tenant. With resource-based policies, you grant Example Corp’s roles direct access to your AgentCore Runtime and AgentCore Runtime endpoint without role chaining. Example Corp’s roles can invoke the agent directly from their own account using their own credentials, while you maintain centralized control over access on the resource side.

    AgentCore Runtime resource-based policy

    The following policy grants Example Corp’s DeveloperRole and AdminRole permission to invoke the agent runtime. This is the first of two resource-based policies required—it controls access to the runtime resource itself. Save this as runtime-policy.json:

    {
      "Version": "2012-10-17",
      "Statement": [
        {
          "Sid": "AllowExampleCorpCrossAccountAccess",
          "Effect": "Allow",
          "Principal": {
            "AWS": [
              "arn:aws:iam::111122223333:role/DeveloperRole",
              "arn:aws:iam::111122223333:role/AdminRole"
            ]
          },
          "Action": "bedrock-agentcore:InvokeAgentRuntime",
          "Resource": "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime"
        }
      ]
    }

    AgentCore Runtime endpoint resource-based policy

    The following policy grants the same roles permission to invoke the AgentCore Runtime endpoint. Without this second policy, requests are allowed at the runtime level but denied at the endpoint level, and the invocation fails. Save this as endpoint-policy.json:

    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "AllowExampleCorpCrossAccountAccess",
                "Effect": "Allow",
                "Principal": {
                    "AWS": [
                        "arn:aws:iam::111122223333:role/DeveloperRole",
                        "arn:aws:iam::111122223333:role/AdminRole"
                    ]
                },
                "Action": "bedrock-agentcore:InvokeAgentRuntime",
                "Resource": "arn:aws:bedrock-agentcore:us-west-2:999999999999:runtime/support-agent-runtime/runtime-endpoint/DEFAULT"
            }
        ] 
    }

    To apply the resource-based policies

    aws bedrock-agentcore-control put-resource-policy \--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime \--policy file://runtime-policy.json \--region us-west-2
    aws bedrock-agentcore-control put-resource-policy \--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT \--policy file://endpoint-policy.json \--region us-west-2

    To verify the resource-based policies

    aws bedrock-agentcore-control get-resource-policy \--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime \--region us-west-2
    aws bedrock-agentcore-control get-resource-policy \--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT \--region us-west-2

    Configure an identity-based policy (Example Corp’s account)

    Resource-based policies alone aren’t sufficient for cross-account access. Example Corp must also attach an identity-based policy to DeveloperRole and AdminRole in their account (111122223333) that allows the same action on your resources. Without this policy on the tenant side, IAM denies the cross-account request even though your resource-based policies allow it.

    Example Corp attaches the following policy to both DeveloperRole and AdminRole:

    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "AllowInvokeAgentRuntime",
                "Effect": "Allow",
                "Action": "bedrock-agentcore:InvokeAgentRuntime",
                "Resource": [
                    "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime",
                    "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT"
                ]
            }
        ] 
    }

    Attach this policy to both DeveloperRole and AdminRole in Example Corp’s account.

    Step 2: Configure cross-account with VPC-restricted access for AnyCompany (Tenant B)

    AnyCompany operates under HIPAA compliance requirements and mandates that all traffic to your agent stays within a private network path. Like Example Corp, AnyCompany needs cross-account access from account 444455556666—but with an additional constraint, requests must originate from their VPC vpc-health1234 through an interface VPC endpoint. Any request from outside this VPC is denied, even if it comes from AnyCompany’s ApplicationRole.

    Resource-based policies (your platform account): To enforce this, you update the resource-based policies on both the AgentCore Runtime and AgentCore Runtime endpoint. Each policy includes an Allow statement that grants ApplicationRole permission to invoke the agent, paired with a Deny statement that blocks any request not originating from vpc-health1234. In the following policy, the Deny statement uses StringNotEquals on aws:SourceVpc . When a request arrives through an interface VPC endpoint, AWS populates this key with the VPC ID. If it doesn’t match vpc-health1234, or if the key is absent because no VPC endpoint was used, the Deny takes effect. Because an explicit Deny overrides any Allow from any policy, this pattern helps ensure that no other identity-based or resource-based policy can inadvertently grant AnyCompany access from outside the VPC. Add the following statements to runtime-policy-v2.json alongside the Example Corp statement from Step 1:

    {
      "Sid": "AllowAnyCompanyCrossAccountAccess",
      "Effect": "Allow",
      "Principal": {
        "AWS": "arn:aws:iam::444455556666:role/ApplicationRole"
      },
      "Action": "bedrock-agentcore:InvokeAgentRuntime",
      "Resource": "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime"
    },
    {
      "Sid": "DenyAnyCompanyOutsideVpc",
      "Effect": "Deny",
      "Principal": {
        "AWS": "arn:aws:iam::444455556666:role/ApplicationRole"
      },
      "Action": "bedrock-agentcore:InvokeAgentRuntime",
      "Resource": "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime",
      "Condition": {
        "StringNotEquals": {
          "aws:SourceVpc": "vpc-health1234"
        }
      }
    }
    

    AgentCore Runtime endpoint resource-based policy

    Add the equivalent statement to endpoint-policy-v2.json:

    {
        "Sid": "AllowAnyCompanyCrossAccountAccess",
        "Effect": "Allow",
        "Principal": {
            "AWS": "arn:aws:iam::444455556666:role/ApplicationRole"
        },
        "Action": "bedrock-agentcore:InvokeAgentRuntime",
        "Resource": "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT"
    },
    {
        "Sid": "DenyHealthFirstOutsideVpc",
        "Effect": "Deny",
        "Principal": {
            "AWS": "arn:aws:iam::444455556666:role/ApplicationRole"
        },
        "Action": "bedrock-agentcore:InvokeAgentRuntime",
        "Resource": "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT",
        "Condition": {
            "StringNotEquals": {
                "aws:SourceVpc": "vpc-health1234"
            }
        }
    }

    Because put-resource-policy replaces the entire policy on a resource, your updated policy files must include both the preceding AnyCompany statments and the Example Corp statements from Step 1.

    Apply the updated resource-based policies

    aws bedrock-agentcore-control put-resource-policy \
    	--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime \
    	--policy file://runtime-policy-v2.json \
    	--region us-west-2 
    
    aws bedrock-agentcore-control put-resource-policy \
    	--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT \
    	--policy file://endpoint-policy-v2.json \
    	--region us-west-2

    Verify the updated policies

    After applying the final policies, verify them using the get-resource-policy command:

    # Verify Agent Runtime policy 
    aws bedrock-agentcore-control get-resource-policy \
    	--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime \
    	--region us-west-2 
    
    # Verify Agent Runtime Endpoint policy 
    aws bedrock-agentcore-control get-resource-policy \
    	--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT \
    	--region us-west-2

    Identity-based policy (AnyCompany’s account)

    AnyCompany must attach an identity-based policy to ApplicationRole in their account 444455556666 that allows the same InvokeAgentRuntime on your resources in account 555555555555. Without this policy on the tenant side, IAM denies the cross-account request even though your resource-based policies allow it.

    AnyCompany attaches the following policy to ApplicationRole:

    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "AllowInvokeAgentRuntime",
                "Effect": "Allow",
                "Action": "bedrock-agentcore:InvokeAgentRuntime",
                "Resource": [
                    "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime",
                    "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT"
                ]
            }
        ] 
    }

    The VPC restriction is enforced entirely on resource account through the resource-based policy condition, AnyCompany’s identity-based policy doesn’t need VPC conditions. This keeps the tenant-side configuration straightforward while you maintain centralized network-level control.

    OAuth authentication considerations

    The policies in this post use SigV4 authentication with specific IAM role principals. If your AgentCore Runtime or AgentCore Gateway is configured with OAuth authentication instead, the principal structure changes. OAuth-authenticated resources require a wildcard principal (“Principal": "*") because the caller identity comes from a JSON Web Token (JWT) validated before policy evaluation. Anonymous or unauthenticated requests are rejected before the policy is evaluated, so the wildcard principal doesn’t grant open access. To restrict OAuth-authenticated requests to a specific VPC, combine the wildcard principal with a VPC condition in the resource-based policy. IAM principal-based condition keys such as aws:PrincipalAccount and aws:PrincipalOrgID aren’t populated in the OAuth authentication context—only supported network-level condition keys (such as aws:SourceVpc, aws:SourceVpce, aws:SourceIp) are available for use in resource-based policies with OAuth. For more details, see Resource-based policies for Amazon Bedrock AgentCore.

    Understanding policy evaluation

    To understand how AWS evaluates these policies when a request arrives, consider the following scenarios:

    Caller or principal Network Identity-based policy (tenant side) Runtime resource-based policy Runtime endpoint resource-based policy Final policy evaluation result
    Example Corp Any network Allows Allows Allows Allowed
    Example Corp Any network Allows Allows Allows Allowed
    AnyCompany From Allows Allows ( does not match) Allows ( does not match) Allowed
    AnyCompany Outside VPC Allows matches matches Denied
    Any other cross-account role Any network Allows No matching No matching Denied
    Any other cross-account role Any network No policy Allows Allows Denied

    Conclusion and next steps

    In this post, you learned how to use resource-based policies on AgentCore to secure a multi-tenant AI platform with distinct access patterns for each tenant:

    • Example Corp gets seamless cross-account integration, their development and admin teams can invoke your AI agent directly from their own AWS account without credential management.
    • AnyCompany gets the strict network-level isolation their compliance team requires, the AI agent is accessible only from within their private VPC, ensuring that interactions involving potential PHI — stay within the controlled network boundary

    Both tenants share the same underlying AgentCore Runtime and AgentCore Runtime endpoint, yet each has tailored security controls enforced at the resource level. his approach avoids per-tenant infrastructure duplication while satisfying each tenant’s security posture, a challenge you likely face when onboarding tenants with different compliance postures. Resource-based policies complement identity-based IAM policies, giving you layered control over which principals can invoke which agents, and from which network paths.

    Next steps

    If you have feedback about this post, submit comments in the Comments section below.


    Satyen Verma

    Satyen Verma

    Satyen is a Software Engineer at AWS building secure and scalable runtime systems for Amazon Bedrock AgentCore. He focuses on enabling reliable, high-performance agentic AI applications for customers worldwide.

    Zohreh Norouzi

    Zohreh Norouzi

    Zohreh is a Security Solutions Architect at AWS. She helps customers make good security choices and accelerate their journey to the AWS Cloud. She has been actively involved in generative AI security initiatives across APJ, using her expertise to help customers build secure generative AI solutions at scale.

    Vijay Kumar Samanthapudi

    Vijay Kumar Samanthapudi

    Vijay is a Software Engineer at AWS building secure and scalable runtime systems for Amazon Bedrock AgentCore. He focuses on enabling reliable, high-performance agentic AI applications for customers worldwide.

    Satveer Khurpa

    Satveer Khurpa

    Satveer is a Sr. WW Specialist Solutions Architect, Amazon Bedrock AgentCore at AWS, specializing in agentic AI security with a focus on AgentCore Identity and Security. He uses his expertise in cloud-based architectures to help clients design and deploy secure agentic AI systems across diverse industries.

    Prajit Pabbati

    Prajit Pabbati

    Prajit is a Software Development Manager at AWS building secure and scalable runtime systems for Amazon Bedrock AgentCore.

    Spring 2026 SOC 1, 2, and 3 reports are now available with 188 services in scope

    Post Syndicated from Baj Bajwa original https://aws.amazon.com/blogs/security/spring-2026-soc-1-2-and-3-reports-are-now-available-with-188-services-in-scope/

    Amazon Web Services (AWS) is pleased to announce that the Spring 2026 System and Organization Controls (SOC) 1, 2, and 3 reports are now available. The reports cover 188 services over the 12-month period from April 1, 2025–March 31, 2026, giving customers a full year of assurance. These reports demonstrate our continuous commitment to adhering to the heightened expectations of cloud service providers.

    Customers can download the Spring 2026 SOC 1 and 2 reports through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact. The SOC 3 report can be found on the AWS SOC Compliance Page and AWS Artifact.

    AWS is excited to be the first cloud service provider to offer compliance reports to customers in NIST’s Open Security Controls Assessment Language (OSCAL), an open-source, machine-readable (JSON) format for security information. The SOC report package in OSCAL format is now available separately in AWS Artifact, marking a milestone towards open, standards-based compliance automation. This machine-readable version of the SOC 1 & 2 reports enables workflow automation to reduce manual processing time and modernize security and compliance processes. Your use-cases for this content are innovative and we want to hear about them via the contact information found in the OSCAL report package.

    AWS strives to continuously bring services into the scope of its compliance programs to help customers meet their architectural and regulatory needs. You can view the current list of services in scope on our Services in Scope page. As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback about SOC compliance.

    To learn more about AWS compliance and security programs, see AWS Compliance Programs.

    If you have feedback about this post, submit comments in the Comments section below.


    Baj Bajwa

    Baj Bajwa

    Baj is a Security Assurance Manager at AWS, where he leads the Global Third-Party Assurance product portfolio within the Compliance and Security Assurance (CSA) organization. He has over 15 years of experience in information security, compliance, and risk management, and holds a master’s degree in cybersecurity. Baj maintains CISSP, CISA, PMP, CCSK, GISF, and ICAgile certifications.

    Tushar-Jain

    Tushar Jain

    Tushar is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives Tushar holds a Master of Business Administration from Indian Institute of Management Shillong, India and a Bachelor of Technology in electronics and telecommunication engineering from Marathwada University, India. He has over 14 years of experience in information security and holds CISM, CCSK and CSXF certifications.

    Michael Murphy

    Michael is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Michael has over 14 years of experience in information security and holds a master’s degree and a bachelor’s degree in computer engineering from Stevens Institute of Technology. He also holds CISSP, CRISC, CISA, and CISM certifications.

    Atulsing Patil

    Atulsing is a Compliance Program Manager at AWS and has over 28 years of consulting experience in information technology and information security management. Atulsing holds a Master of Science in Electronics degree and professional certifications such as CCSP, CISSP, CISM, CDPSE, ISO 42001 Lead Auditor, ISO 27001 Lead Auditor, HITRUST CSF, Archer Certified Consultant, and AWS CCP.

    Jeff Cheung

    Jeff is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives across business lines. Jeff has Bachelors degrees in Information Systems, and Economics from SUNY Stony Brook, and has over 20 years of experience in information security and assurance. Jeff has held professional certifications such as CISA, CISM, and PCI-QSA.

    Noah Miller

    Noah is a Compliance Program Manager at AWS and leads multiple security and privacy initiatives. Noah has 7 years of experience in information security. He has a master’s degree in Cybersecurity Risk Management and a bachelor’s degree in Informatics from Indiana University.

    Will Black

    Will is a Compliance Program Manager at AWS where he leads multiple security and compliance initiatives. Will has 10 years of experience in compliance and security assurance and holds a degree in Management Information Systems from Temple University. Additionally, he is a PCI Internal Security Assessor (ISA) for AWS and holds the CCSK and ISO 27001 Lead Implementer certifications.

    Allen Beam

    Allen is a Compliance Program Manager at AWS supporting third-party security and privacy compliance initiatives. He has over 10 years of experience in external IT security audits, security control design and implementation, and audit readiness and control deficiency remediation. He has a Bachelor’s Degree in Economics and Finance from James Madison University.

    Ziv Wand

    Ziv is a Compliance Program Manager at AWS and leads multiple security and privacy initiatives. Ziv has over 6 years of experience in information security assurance, external IT security audits, security control design and implementation, and audit readiness. He holds a Bachelor of Science in Management Information Systems from Binghamton University.

    Shalini Mishra

    Shalini is a Compliance Program Manager at AWS. She has over 10 years of experience leading end-to-end compliance programs across ISO, SOC, and cloud security frameworks, with deep expertise in third-party risk management and enterprise governance. Shalini holds a Master of Science degree in Information Systems and CRISC certification.