In a recent evaluation of AI models’ cyber capabilities, current Claude models can now succeed at multistage attacks on networks with dozens of hosts using only standard, open-source tools, instead of the custom tools needed by previous generations. This illustrates how barriers to the use of AI in relatively autonomous cyber workflows are rapidly coming down, and highlights the importance of security fundamentals like promptly patching known vulnerabilities.
[…]
A notable development during the testing of Claude Sonnet 4.5 is that the model can now succeed on a minority of the networks without the custom cyber toolkit needed by previous generations. In particular, Sonnet 4.5 can now exfiltrate all of the (simulated) personal information in a high-fidelity simulation of the Equifax data breach—one of the costliest cyber attacks in historyusing only a Bash shell on a widely-available Kali Linux host (standard, open-source tools for penetration testing; not a custom toolkit). Sonnet 4.5 accomplishes this by instantly recognizing a publicized CVE and writing code to exploit it without needing to look it up or iterate on it. Recalling that the original Equifax breach happened by exploiting a publicized CVE that had not yet been patched, the prospect of highly competent and fast AI agents leveraging this approach underscores the pressing need for security best practices like prompt updates and patches.
AI models are getting better at this faster than I expected. This will be a major power shift in cybersecurity.
Root cause analysis during incidents is one of the most time-consuming and stressful parts of operating cloud applications. Engineers must quickly correlate telemetry data across multiple services, review deployment history, and understand complex application dependencies—all while under pressure to restore service. AWS DevOps Agent changes this paradigm by bringing autonomous investigation capabilities to your operations team, reducing mean time to resolution (MTTR) from hours to minutes.
However, the effectiveness of AWS DevOps Agent depends heavily on how you configure your Agent Spaces which control resource access boundaries. An Agent Space that’s too narrow misses critical context during investigations. One that’s too broad introduces performance overhead and complexity. This post provides best practices for setting up Agent Spaces that balance investigation capability with operational efficiency, drawing from our experience onboarding early customers and using DevOps agent across our own teams.
By the end of this post, you’ll understand how to structure Agent Spaces for optimal investigation accuracy, determine the right scope of resource access, and use Infrastructure as Code (IaC) to streamline deployment. Let’s start by understanding the foundational concept that makes all of this possible: the Agent Space itself.
What is an Agent Space and Why Does It Matter?
An Agent Space is a logical container that defines what AWS DevOps Agent can access and investigate. Think of it as the agent’s operational boundary—it determines which cloud accounts the agent can query, which third-party integrations are available, and who can interact with investigations.
Agent Spaces are critical because AWS DevOps Agent needs sufficient context to perform accurate root cause analysis.
When an incident occurs, the agent:
Learns your resources and their relationships across accounts
Correlates telemetry data from logs, metrics, and traces
Reviews recent changes including deployments and configuration updates
Generates and tests hypotheses by querying additional data sources
Figure 1: Agent Space Topology
If the Agent Space doesn’t include access to a critical account or integration, the agent might miss the root cause entirely. Conversely, an overly broad Agent Space introduces performance challenges as the agent considers more resource permutations during investigations.
Understanding these trade-offs between scope and performance is essential. The question becomes: how do you determine the right boundaries for your specific organization and operational model?”
Part 1: Design your Agent Space architecture
We recommend thinking about Agent Space boundaries the same way you think about on-call responsibilities: grant access to accounts relevant to the application, but separate production from non-production environments.
This approach provides several benefits:
Familiar mental model – Operations teams already understand on-call boundaries
Appropriate investigation scope – Mirrors how human engineers would investigate incidents
Two-way door decision – You can expand or narrow Agent Space scope as needs evolve
Performance balance – Provides sufficient context without overwhelming the agent
Determine Your Agent Space Boundaries
Start by mapping your application architecture to Agent Space boundaries and consider the following questions:
What defines a logical application?
Does your team own multiple independent applications? If so, create separate Agent Spaces.
Is it a monolith spanning multiple accounts? Then one Agent Space with cross-account access makes sense.
How do you organize on-call rotations?
Separate teams for production versus non-production suggests separate Agent Spaces.
One team handling all environments might work with one Agent Space per application.
What are your investigation patterns?
Do production incidents require querying dependent services in other accounts? Include those accounts.
Are environments completely isolated? Keep Agent Spaces separate.
Figure 2: Agent Space boundaries mirror on-call team responsibilities
Common Agent Space Patterns and Decision Points
Beyond the basic single-application pattern, organizations encounter more complex scenarios that require careful consideration. Here are critical patterns to address that we’ve seen customers successfully adopt:
Pattern 1: Investigations Spanning Multiple Teams. Large organizations with multiple teams (example: 3 teams managing 100+ production accounts) encounter situations where an issue originates in Team A’s infrastructure but the root cause lies in Team B’s services. The question becomes: how do you enable collaboration across Agent Spaces?
Recommended approach: Create application-specific Agent Spaces that include read-only access to shared resource accounts e.g. dependencies. Establish clear on-call escalation procedures and add them as runbooks when investigations identify cross-team root causes for efficient communication (e.g. via chat in Slack). Configure the shared service team’s resources with tags identifying which applications use them (example: app-id: ecommerce-frontend). Following a consistent tagging strategy provides investigation context for shared resources while maintaining clear resource ownership.
Pattern 2: Shared Services and Network Operations Center (NOC) Teams. Some organizations have centralized teams that provide and support shared infrastructure services (databases, networking, monitoring, security) used by multiple applications across the organization. These NOC or central operations teams need visibility into their services without requiring access to every application’s Agent Space.
Recommended approach: Create a dedicated Agent Space for the shared service team and configure an Agent Space scoped to the shared service team’s infrastructure and operational responsibilities:
Include AWS accounts containing shared databases, network infrastructure, centralized logging, and monitoring systems
Add relevant CloudFormation stacks for shared platform services
Configure IAM roles that provide read-only access to the specific resources the team supports
Include runbooks and operational procedures specific to the shared services
This follows the same principle as application-specific Agent Spaces: one Agent Space per on-call team, even when that Agent Space’s scope spans multiple applications. While shared services teams manage specific infrastructure domains, SRE teams often face an even larger challenge: operational responsibility for hundreds or thousands of applications at enterprise scale.
Pattern 3: Central Operations Teams Managing Many Applications. Central operations teams responsible for operational tooling across hundreds or thousands of applications can efficiently manage Agent Spaces at scale using Infrastructure as Code.
Recommended approach: Use the AWS CDK or Terraform samples available as starting points. These samples enable teams to:
Define a standardized Agent Space template with your organization’s required IAM roles, integrations, resource boundaries and governance tags
Deploy Agent Spaces programmatically as part of application onboarding workflows
Enforce compliance through AWS Config rules or service control policies
Track all Agent Spaces through consolidated billing and tagging (application-id, team, cost-center, environment)
Central operations teams manage the templates and governance policies, while application teams operate within those guardrails. This approach scales to thousands of applications with consistent configuration and automated deployment. AWS DevOps agent allows limiting agent access in an AWS account and controlling access for users to the operator console for teams to manage Agent Space access at scale.
Figure 3: Enterprise scale pattern using Infrastructure as Code
Now that you understand how to design Agent Space boundaries aligned with your team structure and scale requirements, let’s walk through the practical implementation steps to bring these architectural patterns to life.
Part 2: Implement your Agent Space architecture
This section walks you through the practical steps of creating your first Agent Space—from verifying prerequisites and configuring IAM roles across accounts to integrating observability tools, setting up access controls, and testing your configuration to ensure investigations have the context they need.
Step 1: Agent Space Prerequisites
Before setting up your first Agent Space, ensure you have:
AWS accounts – At least one AWS account where your application resources run
IAM permissions – Sufficient access to create IAM roles and policies across accounts. AWS DevOps Agent requires two distinct sets of IAM permissions:
Agent Space role permissions – The IAM role that AWS DevOps Agent assumes to query your AWS resources, access CloudWatch Logs, and discover topology. This role requires the AIOpsAssistantPolicy managed policy plus additional permissions for AWS Support and expanded capabilities. See the CLI onboarding guide for the complete role configuration.
Operator app role permissions – The IAM role that controls what human operators can do in the AWS DevOps Agent web application, such as starting investigations, viewing results, and creating AWS Support cases. This role is separate from the agent’s investigation permissions.
Service Control Policies (SCPs) – Verify that your organization’s SCPs allow AWS DevOps Agent API actions. Common issue: Teams complete Agent Space setup but investigations fail because SCPs block aidevops:* actions or bedrock:InvokeModel actions. Review your AWS Organization’s SCPs and add exceptions for DevOps Agent if needed. Note that DevOps Agent and Amazon Bedrock inference are not impacted by policies that restrict customer content to specific AWS regions—Bedrock may use US regions other than US East (N. Virginia) for stateless inference.
Observability tools – At minimum, Amazon CloudWatch (automatically available via IAM roles) and Amazon CloudTrail. For comprehensive investigations, integrate Application Performance Monitoring tools like Datadog, Dynatrace, New Relic, Grafana, or Splunk. See Connecting telemetry sources for supported integrations.
Understanding third-party integration configuration – Some third-party tools require a two-step configuration process:
Account-level registration – Tools that use OAuth (like GitHub, Dynatrace) must first be registered at the AWS account level through the DevOps Agent console. This establishes OAuth credentials that are shared across all Agent Spaces in your account.
Agent Space-level association – After registration, each Agent Space individually specifies which resources from that tool to use. For example, after registering GitHub once, Agent Space “EcommerceProd” can associate only production repositories while Agent Space “EcommerceNonProd” associates development repositories.Other tools like Datadog, New Relic, and Splunk can be directly associated with an Agent Space using API keys or tokens without separate account-level registration. CloudWatch requires no additional configuration beyond IAM roles.
Source control – GitHub or GitLab repository access for code context and deployment correlation (optional but highly recommended)
IaC tooling – AWS CDK (TypeScript/Python), Terraform, AWS CLI, or AWS Management Console for Agent Space deployment
With prerequisites verified, you’re ready to create your Agent Space and establish the IAM trust relationships that enable investigations.
Step 2: Create an Agent Space
AWS DevOps Agent requires IAM roles in each AWS account within the Agent Space boundary. The agent assumes these roles to query CloudWatch Logs, describe resources, and build application topology.
The AWS DevOps Agent is designed to retrieve operational data from multiple AWS Regions across all AWS accounts that you grant access to within the configured Agent Space, enabling comprehensive visibility into distributed infrastructure and applications regardless of their geographic deployment, while supporting multiple accounts through a configuration process that involves creating IAM roles with appropriate trust policies and permissions in secondary accounts
Option A: Use the AWS Console wizard Navigate to the AWS DevOps Agent console and choose Create Agent Space and follow the guided setup to create IAM roles in each target account.
Figure 4: Creating an Agent Space in the Console
The setup wizard helps in configuring cross-account trust relationships.
Figure 5: Multiple account configuration for your Agent Space
Option B: Use Infrastructure as Code (Recommended) We provide sample CDK and Terraform templates that automate Agent Space creation and IAM role deployment across multiple accounts.
For detailed instructions on setting up IAM roles and permissions across accounts, see the CLI Onboarding Guide.
Once your Agent Space exists and has access to AWS accounts, the next critical step is connecting the observability and development tools that provide investigation context beyond AWS native services.
Step 3: Configure Integrations
AWS DevOps Agent investigates incidents by correlating data from multiple sources. The more context available, the more accurate the root cause analysis.
Recommended integrations by priority:
Amazon CloudWatch – Provides logs, metrics, and traces from AWS services. The agent queries CloudWatch Logs Insights automatically during investigations. No additional configuration is needed if IAM roles are properly configured.
Application Performance Monitoring tools – Datadog, Dynatrace, New Relic, and Splunk provide distributed tracing, custom metrics, and application-level context. Configure via Agent Space integrations in the AWS Console.
Code repositories – GitHub or GitLab integration enables the agent to review recent deployments and code changes. Requires OAuth or personal access token.
CI/CD pipelines – GitHub Actions or GitLab workflows help the agent correlate incidents with deployment timing. Configured alongside code repository integration.
Communication Channels – Slack and ServiceNow integration enables DevOps Agent to post real-time investigation updates to team channels and automatically update incident tickets with findings, root cause analysis, and recommended mitigation steps throughout the investigation lifecycle.
Advanced Integrations
Beyond built-in integrations, AWS DevOps Agent supports webhook triggered investigations and custom MCP (Model Context Protocol) servers so you can bring-your-own observability tools.
Webhook configuration for investigation triggers Webhooks allow external systems (Grafana, Prometheus, PagerDuty, custom monitoring tools) to automatically trigger DevOps Agent investigations when incidents occur. Each Agent Space receives a unique webhook URL that accepts JSON payloads describing the incident.
Common configuration pitfalls:
Webhook authentication: Webhooks use HMAC signatures for security. Store the webhook secret in AWS Secrets Manager and rotate it according to your security policies.
Payload format: Ensure your monitoring tool sends incident context including timestamps, affected resources, and symptom descriptions. Richer context enables more accurate investigations.
Bring-your-own MCP servers If you use observability tools beyond the built-in integrations (Grafana, Prometheus, custom telemetry systems), you can connect them via MCP servers. MCP servers expose your tool’s data through a standardized protocol that DevOps Agent queries during investigations.
Key requirements for MCP servers:
Publicly accessible HTTPS endpoint: MCP servers must be reachable from the public internet. VPC-hosted servers are not currently supported.
Read-only tools only: For security, only expose MCP tools that perform read operations. Write operations introduce prompt injection risks.
Tool allowlisting: Register MCP servers at the account level, then selectively enable specific tools per Agent Space. Don’t grant access to all tools—choose only those relevant to investigations.
Common MCP setup errors:
Authentication misconfiguration: MCP servers support OAuth 2.0 or API key authentication. Verify your OAuth client credentials are correct and that token exchange URLs are accessible from AWS infrastructure.
Tool name length: MCP tool names have a maximum length of 64 characters. Longer names will fail registration.
Endpoint URL format: Use the full HTTPS URL including path. Example: https://mcp.example.com/v1/mcp not just mcp.example.com.
For comprehensive MCP server setup including authentication configuration, see Connecting MCP Servers.
Testing your integrations After configuring webhooks or MCP servers, trigger a test investigation to verify connectivity:
For webhooks: Send a test payload from your monitoring tool and verify the investigation starts in the DevOps Agent web app
For MCP servers: Start an investigation manually and check the agent journal to confirm it successfully called your MCP tools
Review any errors in AWS CloudTrail logs which capture all DevOps Agent API calls including integration attempts
With your data sources connected, you now need to ensure the right people have appropriate access to investigations while maintaining security boundaries.
Step 4: Configure Access Controls
Agent Spaces support fine-grained access controls to ensure only authorized team members can interact with investigations.
Access control considerations:
Who should view investigations? Typically on-call engineers, SREs, and DevOps engineers. Consider including security teams for security-related incidents.
Who should create AWS Support cases? Typically on-call leads and senior engineers. Restrict this permission to prevent excessive case creation.
Who should modify Agent Space configuration? Typically central operations or infrastructure teams. Separate this from day-to-day investigation access.
IAM-based access control:
AWS DevOps Agent uses IAM policies to control access to Agent Spaces. Attach policies to IAM users, groups, or roles:
AWS DevOps Agent operates within your AWS environment with privileged access to operational data across multiple accounts. While general security foundations apply, Agent Space configuration introduces specific considerations. For comprehensive security guidance, see the AWS DevOps Agent Security documentation.
Access controls are in place—now it’s time to validate that your Agent Space configuration provides the investigation coverage you need.
Step 5: Test and Iterate
Agent Space configuration is a two-way door decision. Start with a focused scope and expand based on investigation results.
Testing your Agent Space:
Trigger a test investigation using the AWS DevOps Agent web app.
Start an investigation and provide symptoms such as “High latency on /api/checkout endpoint”.
Observe which resources the agent queries.
Review investigation completeness. Did the agent identify the root cause?
Were any accounts or services missing from the investigation?
Did the agent have sufficient telemetry data?
Adjust Agent Space boundaries based on results.
Add accounts if investigations lack context.
Add integrations if telemetry gaps exist.
Narrow scope if performance degrades.
Conclusion
AWS DevOps Agent transforms incident response from a manual, time-consuming process into an autonomous, data-driven investigation. However, the agent’s effectiveness depends on proper Agent Space configuration. By following the on-call based approach—granting access to accounts relevant to your application while separating production from non-production environments—you provide sufficient context for accurate root cause analysis without introducing unnecessary complexity.
Key takeaways:
Think on-call boundaries – Agent Space scope should mirror how your team investigates incidents
Use Infrastructure as Code – CDK and Terraform templates ensure consistent, repeatable deployments
Integrate observability tools – More data sources equals more accurate investigations
Iterate based on results – Expand or narrow Agent Space scope as investigation patterns emerge
We’re committed to making AWS DevOps Agent easier to adopt and more accurate in solving customer problems. Your Agent Space setup is the foundation for achieving fast, reliable incident resolution. Have questions or feedback? Leave a comment below.
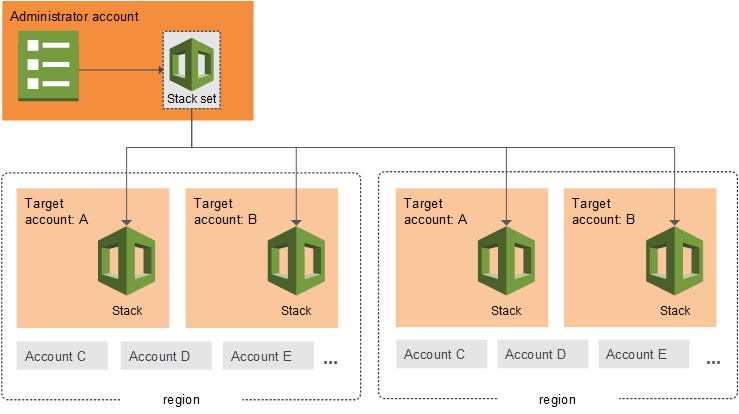
AWS CloudFormation enables you to model and provision your cloud application infrastructure as code-base templates. Whether you prefer writing templates directly in JSON or YAML, or using programming languages like Python, Java, and TypeScript with the AWS Cloud Development Kit (CDK), CloudFormation and CDK provide the flexibility you need. For organizations adopting multi-account strategies, CloudFormation StackSets offers a powerful capability to deploy resources across multiple regions and accounts in parallel.
In 2025, we delivered a comprehensive set of major enhancements focused on three core areas: reducing dev-test cycle through early validation, improving deployment safety with improved configuration drift management, and integrating IaC context to AI-powered development tools.
These launches address common pain points in infrastructure development workflows, from catching deployment errors before resource provisioning to managing configuration drift systematically. The features span the entire development lifecycle, from template authoring in your IDE to multi-account deployments at scale.
This blog provides an overview of the key capabilities we launched in 2025 and how they improve your infrastructure development workflow.
Accelerating Development Cycles
Early Validation & Enhanced Troubleshooting: Pre-Deployment Error Detection
CloudFormation now validates your templates during change set (preview of infrastructure changes before deployment) creation, catching common deployment errors before resource provisioning begins. The validation checks for invalid property syntax, resource name conflicts with existing resources in your account, and S3 bucket emptiness constraints on delete operations.
Figure 1: Pre-deployment validations view
When validation fails, the change set status shows ‘FAILED’ with detailed information about each issue, including the property path where problems occur. This early feedback helps you fix issues faster rather than waiting for deployment failures.
Figure 2: Validation of Invalid ENUM value for nested property
Improved Deployment troubleshooting
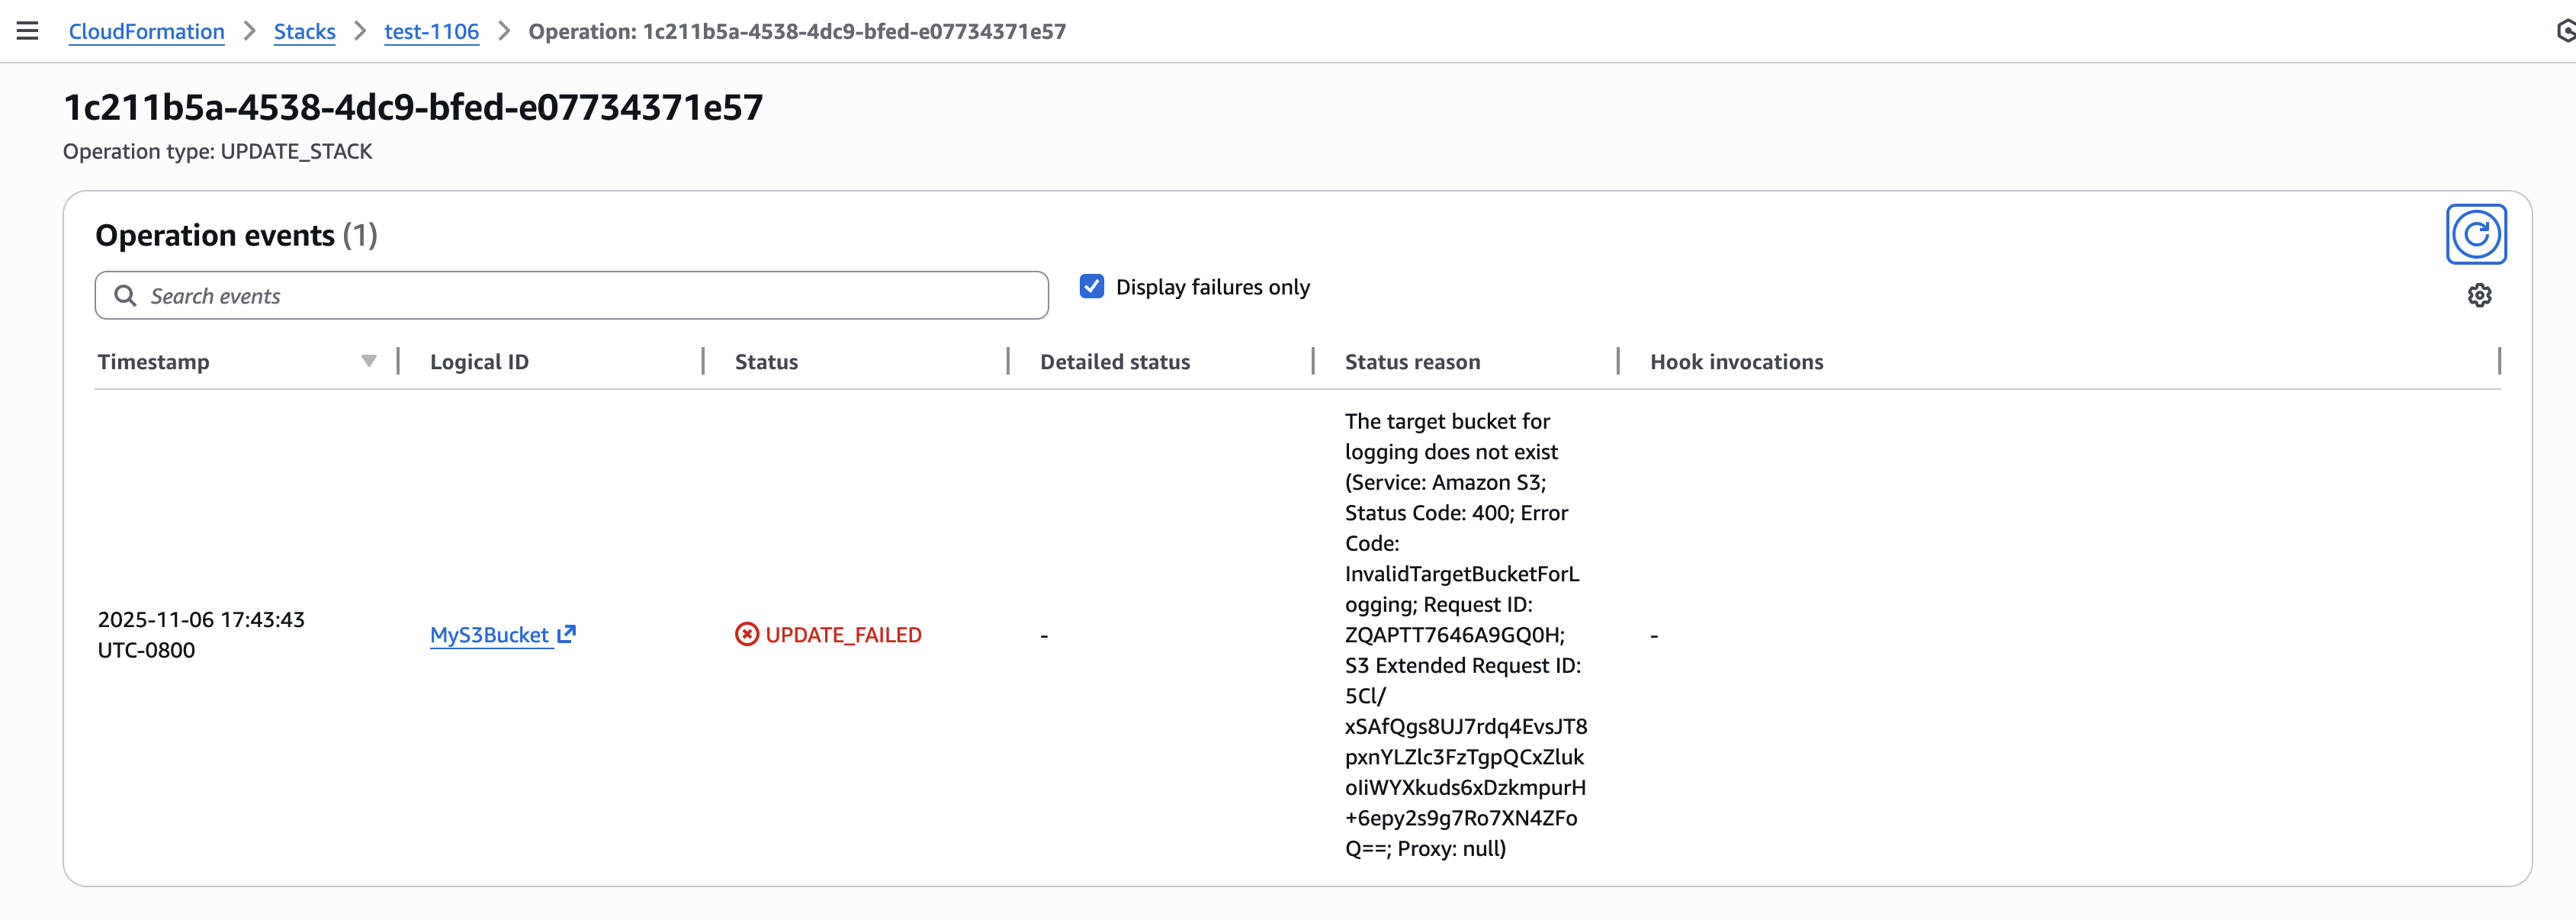
For runtime errors that occur during deployment, every stack operation now receives a unique operation ID. You can filter stack events by operation ID to quickly identify root causes, reducing troubleshooting time from minutes to seconds. The new describe-events API provides grouped access to events. You can query events for a specific operation, filter to FAILED status events, and extract the root cause without parsing through the entire stack event history.
CloudFormation IDE Experience: Language Server Protocol Integration
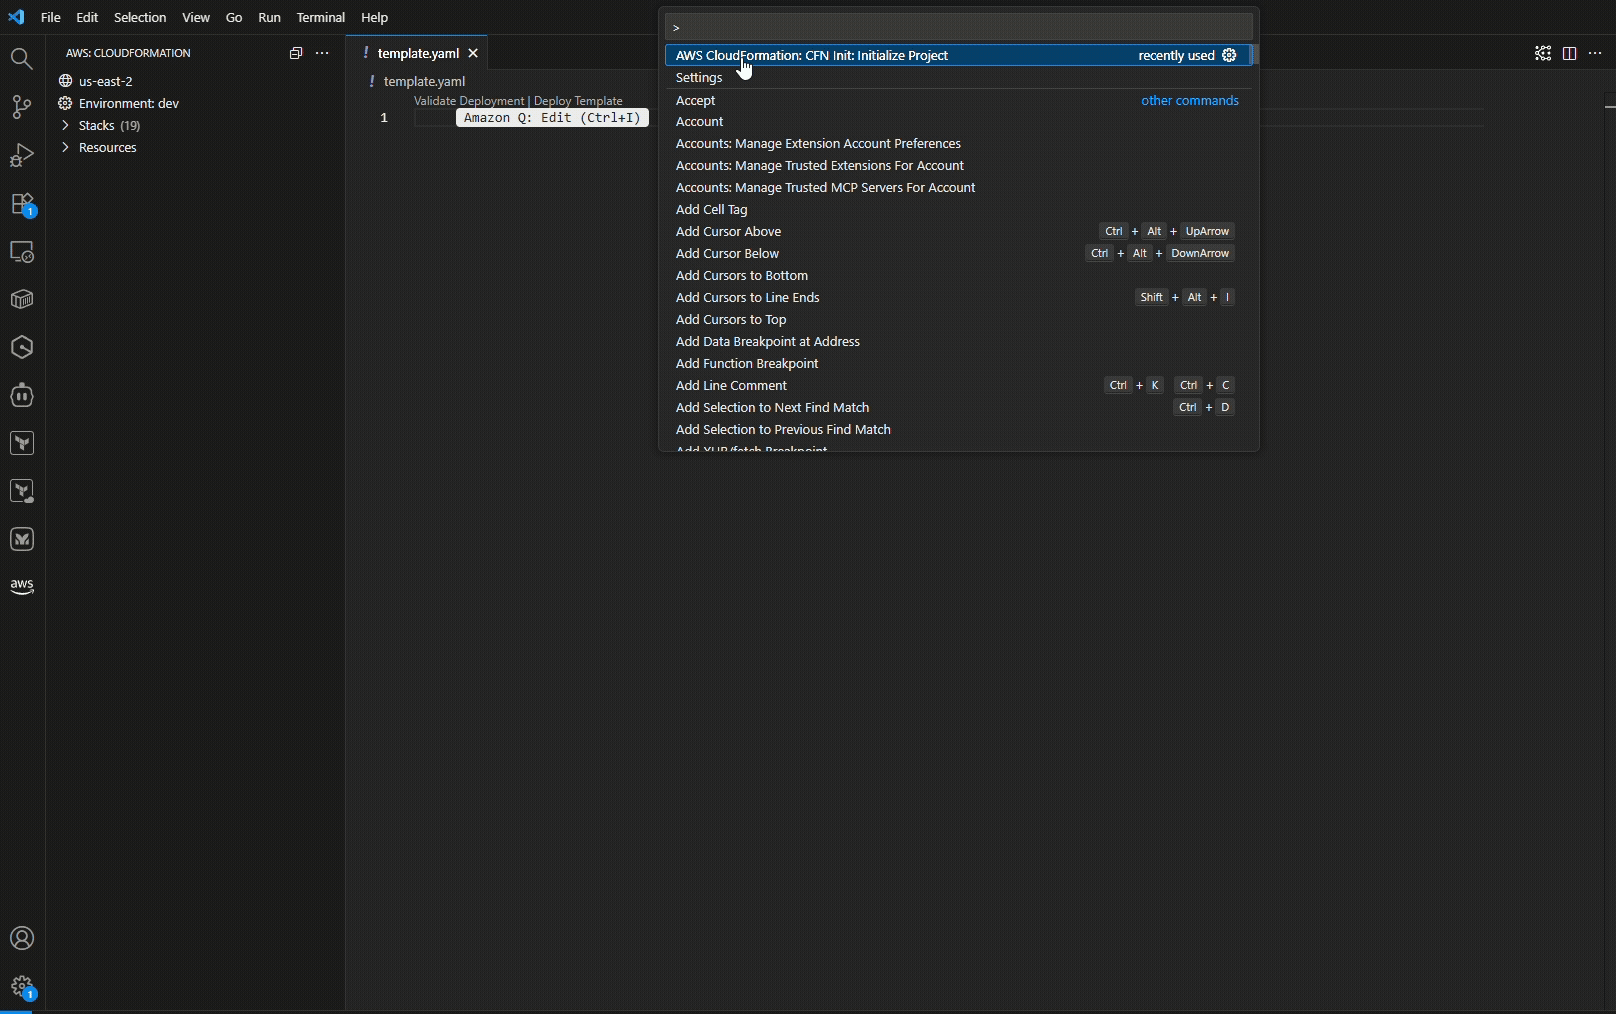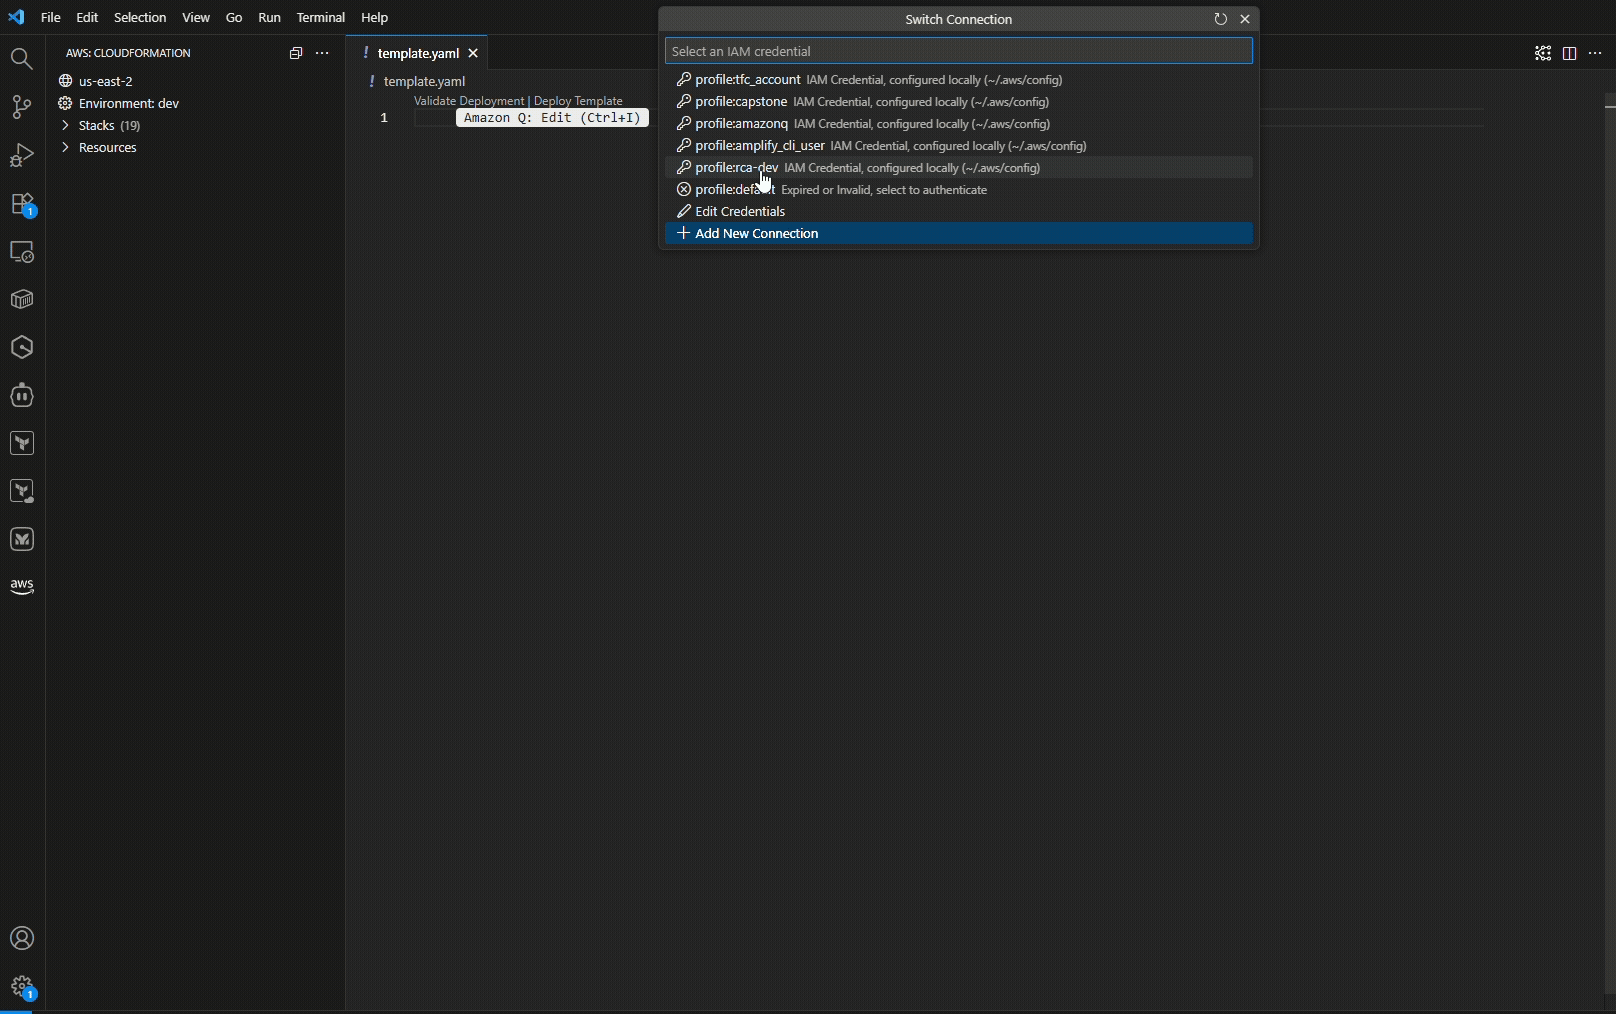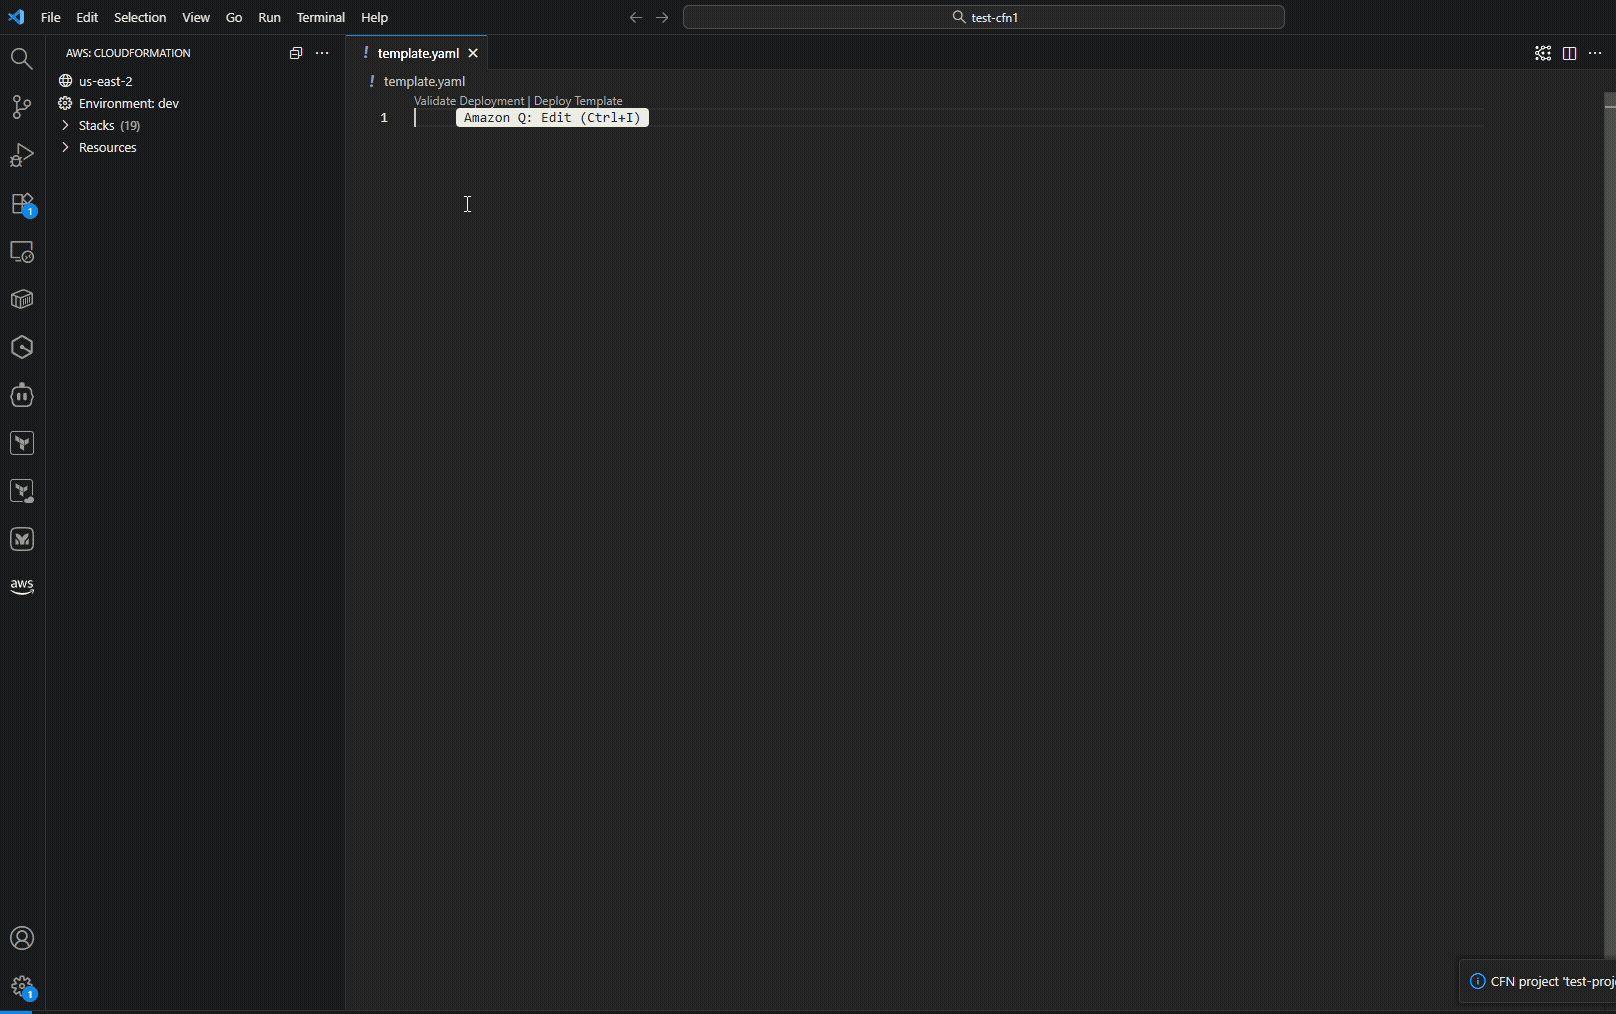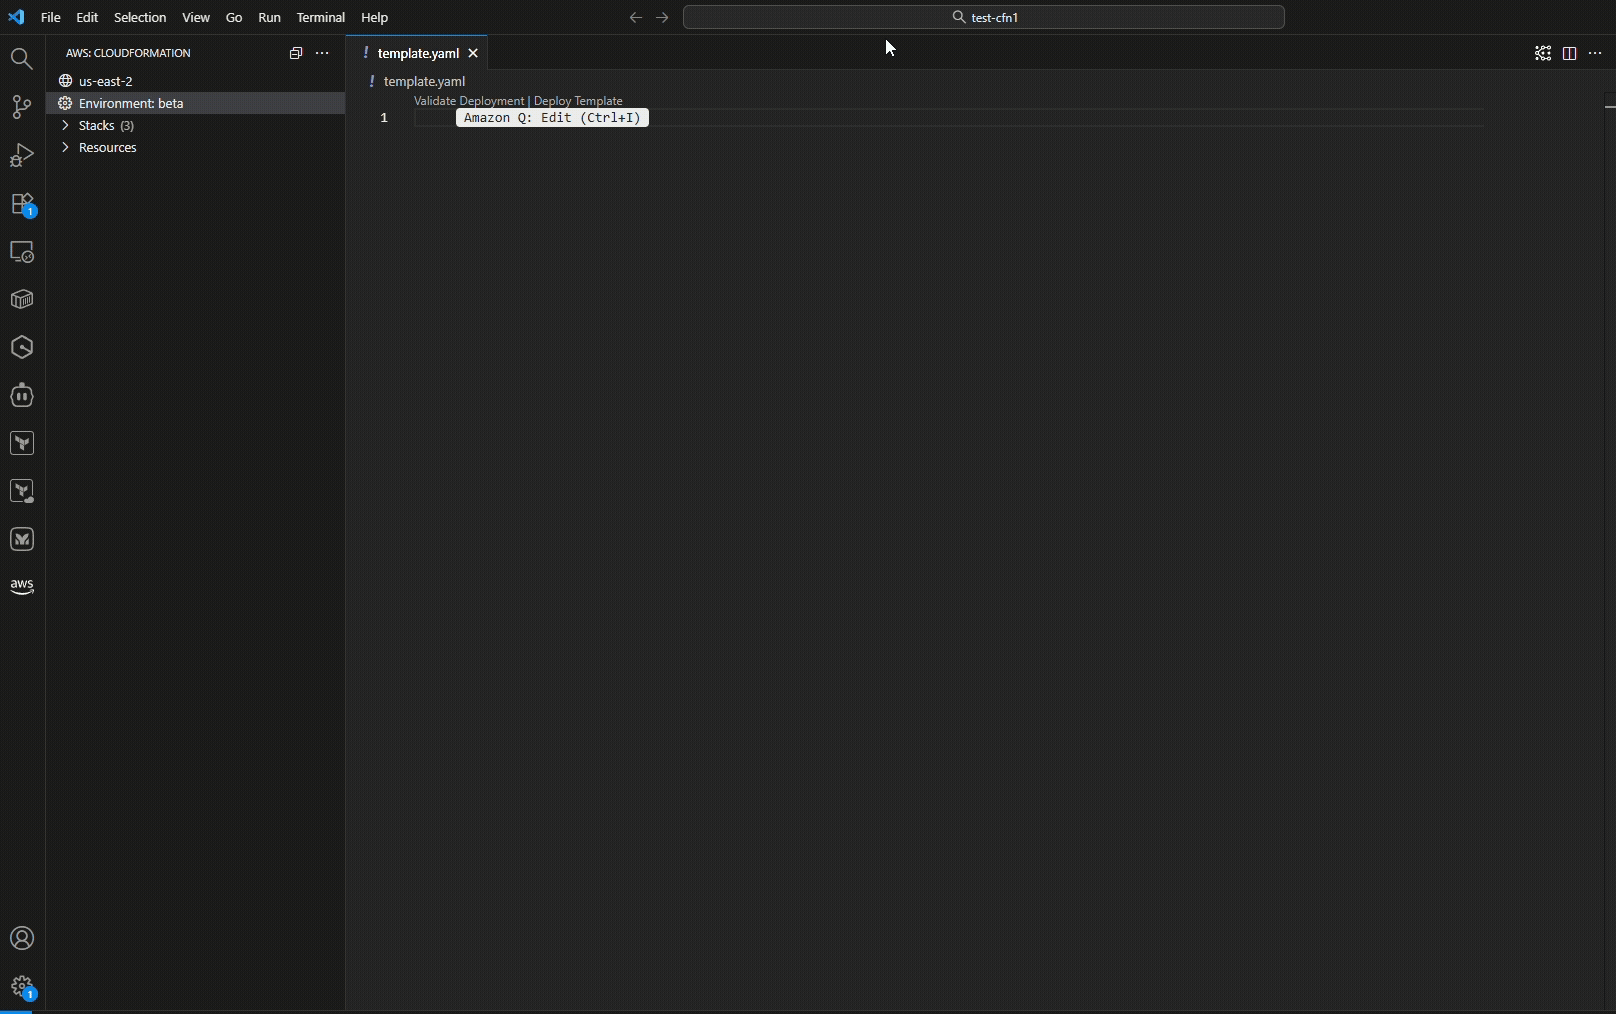
We launched the AWS CloudFormation Language Server, bringing end-to-end infrastructure development directly into your IDE. Available through the AWS Toolkit for Visual Studio Code, Kiro, and other compatible IDEs, this capability transforms how you author CloudFormation templates.
Figure 1: Initializing a CloudFormation project with environment configuration
The Language Server provides context-aware auto-completion that understands CloudFormation semantics. When you define resources, it suggests only required properties automatically, while optional properties appear on hover. Built-in validation catches issues before deployment integrating early validation capabilities, flagging invalid resource properties, missing IAM permissions, and security policy violations using CloudFormation Guard.
Figure 2: Hover information displaying optional properties and their documentation
The drift-aware deployment view highlights differences between your template and deployed infrastructure, helping you spot configuration changes made outside CloudFormation. The Language Server also provides semantic navigation features, go-to-definition for logical IDs, find-all-references for resource dependencies, and hover documentation that pulls from the CloudFormation resource specification. These features work across intrinsic functions like !Ref, !GetAtt, and !Sub, understanding the CloudFormation template structure. By integrating validation and real-time feedback directly into your authoring experience, the Language Server keeps you in flow state, reducing context switching between your IDE, AWS Console, and documentation.
Figure 3: Type-aware completions for intrinsic functions like !GetAtt & !Ref
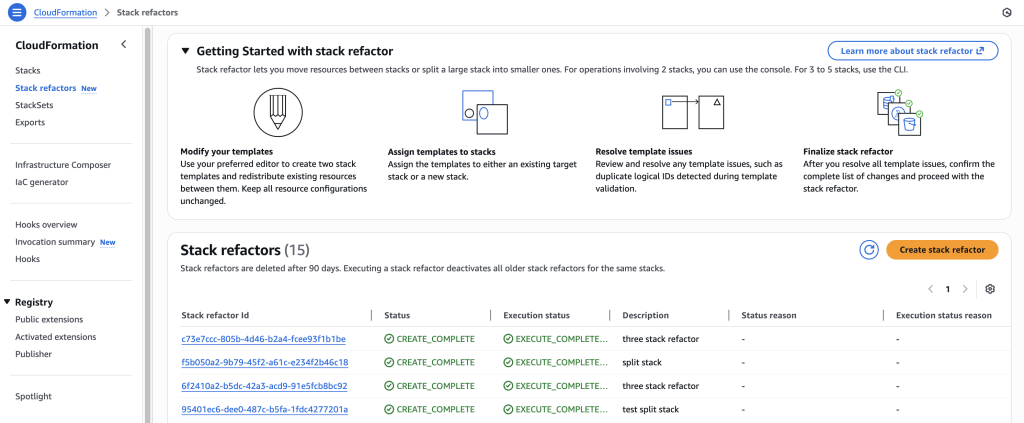
Stack Refactoring: Adapt your infrastructure to your organization evolution
Stack Refactoring enables you to reorganize your CloudFormation and CDK infrastructure without disrupting deployed resources. You can move resources between stacks, rename logical IDs, and decompose monolithic stacks into focused components while maintaining resource stability and operational state.
Whether you’re modernizing legacy stacks, aligning infrastructure with evolving architectural patterns, or improving long-term maintainability, Stack Refactoring adapts your CloudFormation and CDK organization to changing requirements. The console and CDK experience, launched this year, extends the earlier CLI capability, making refactoring accessible through your preferred interface.
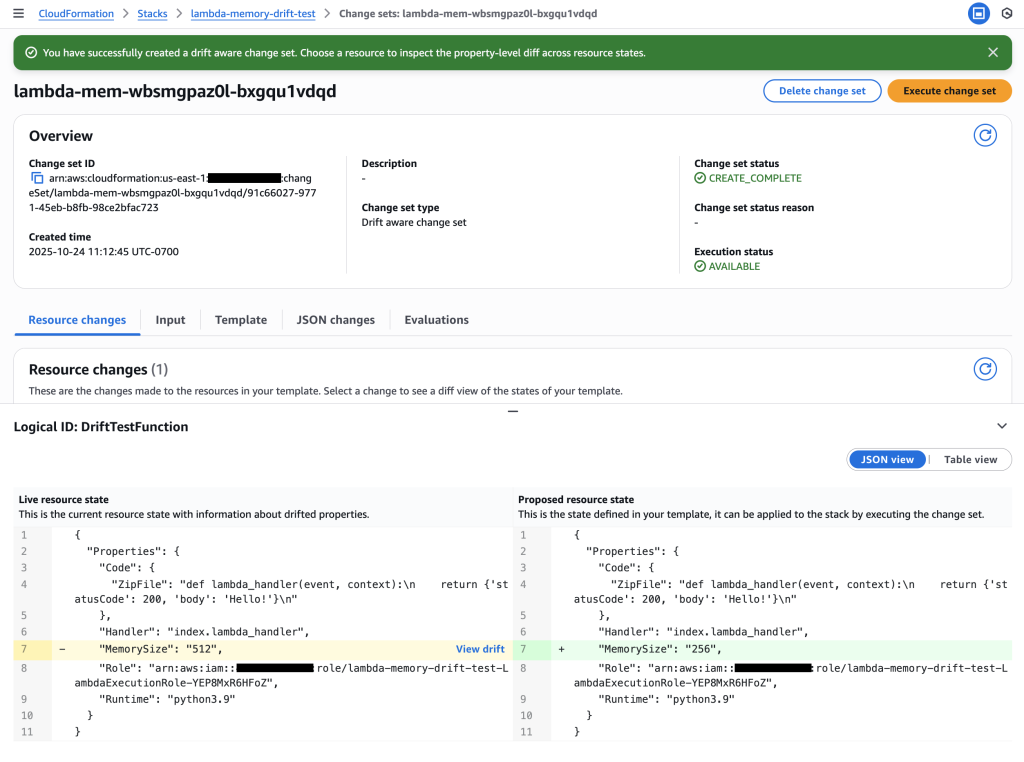
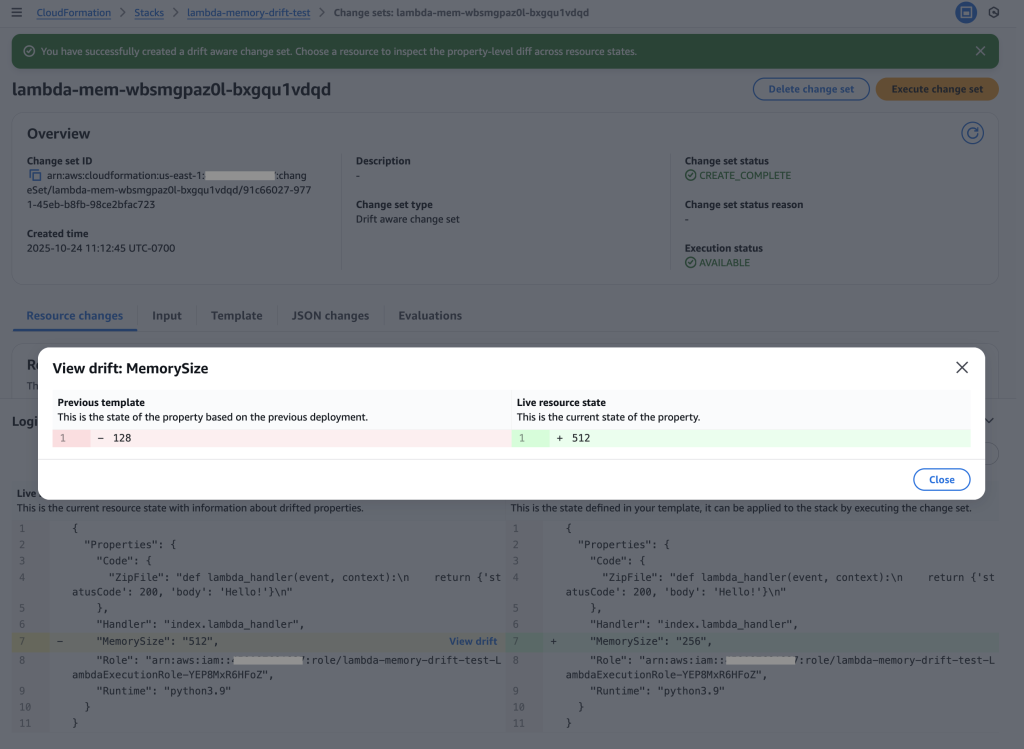
Configuration drift occurs when infrastructure managed by CloudFormation is modified through the AWS Console, SDK, or CLI. Drift-aware change sets address this challenge by providing a three-way comparison between your new template, last-deployed template, and actual infrastructure state.
Figure 4: Examine the drift-aware change set to see the dangerous memory reduction that would occur
This capability helps you prevent unexpected overwrites of drift. If your change set preview shows unintended changes, you can update your template values and recreate the change set before deployment. During execution, CloudFormation matches resource properties with template values and recreates resources deleted outside of CloudFormation.
Drift-aware change sets enable you to systematically revert drift and keep infrastructure in sync with templates, strengthening reproducibility for testing and disaster recovery while maintaining your security posture.
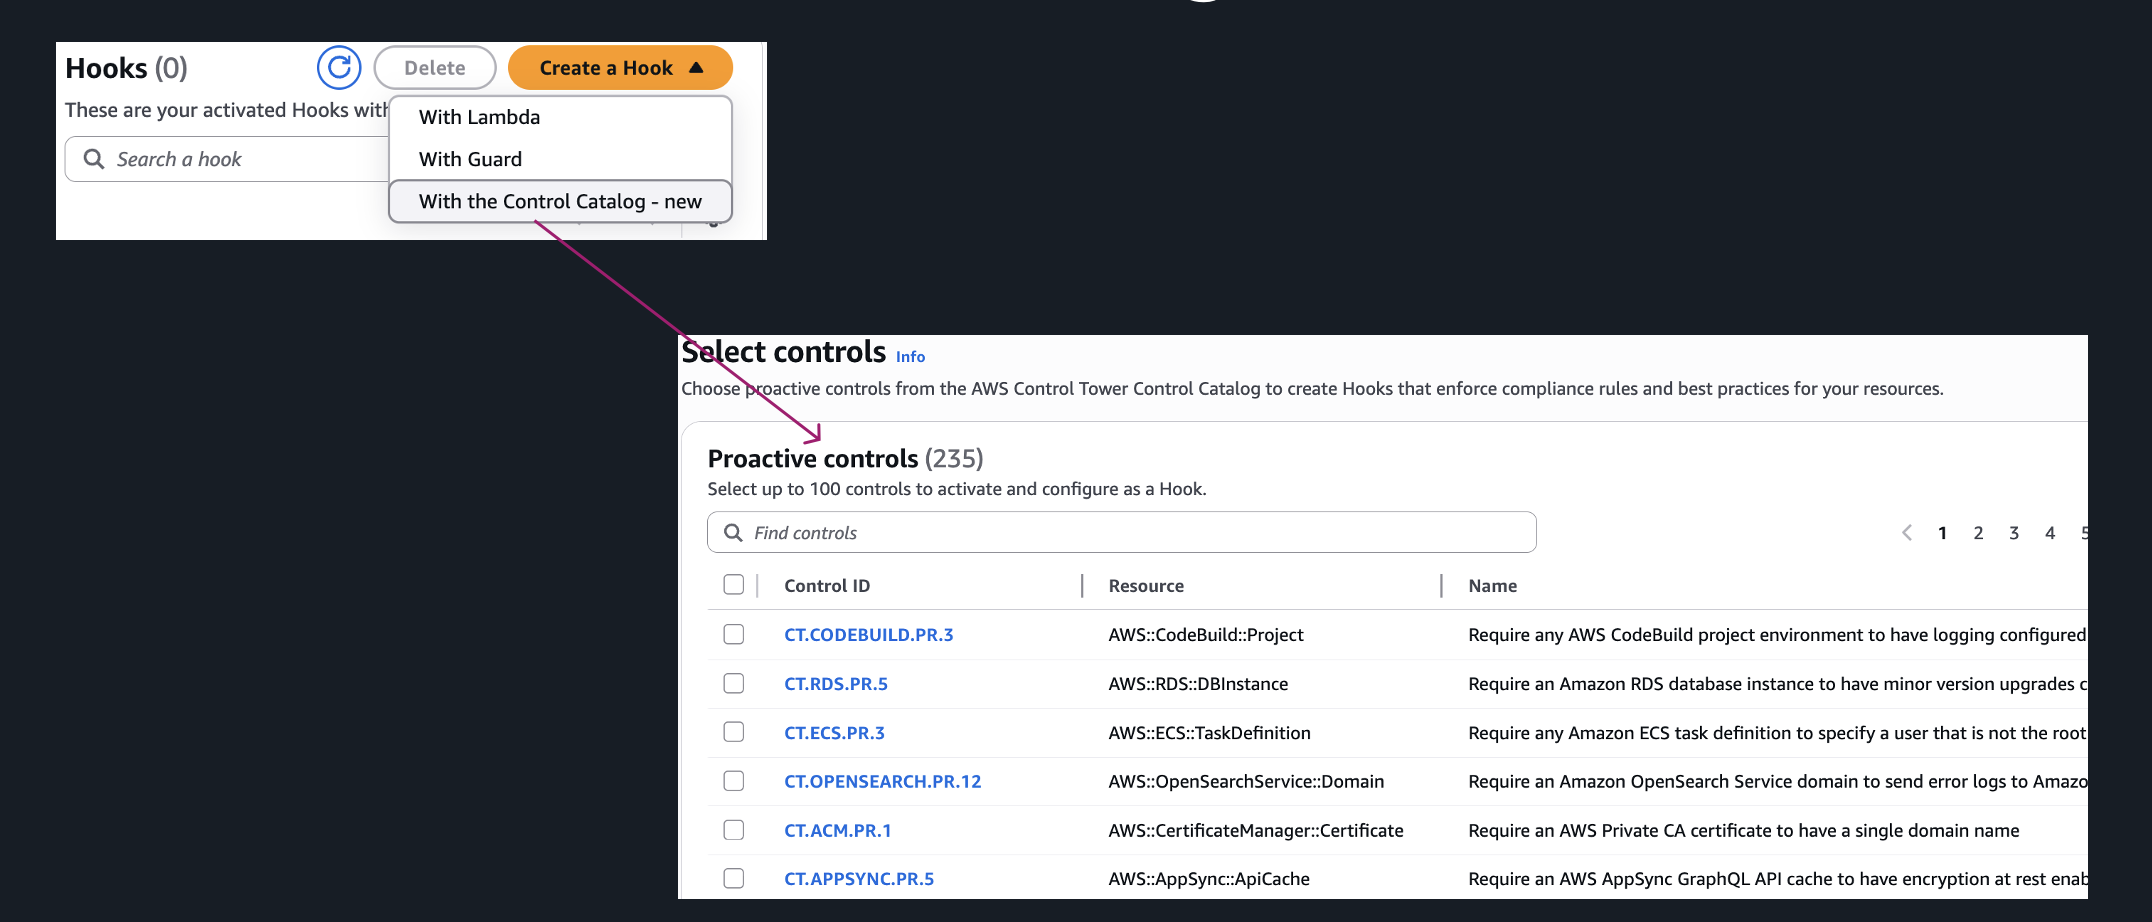
AWS CloudFormation Hooks now supports managed proactive controls, enabling customers to validate resource configurations against AWS best practices without writing custom Hooks logic. Customers can select controls from the AWS Control Tower Controls Catalog and apply them during CloudFormation operations. When using CloudFormation, customers can configure these controls to run in warn mode, allowing teams to test controls without blocking deployments and giving them the flexibility to evaluate control behavior before enforcing policies in production. This significantly reduces setup time, eliminates manual errors, and ensures comprehensive governance coverage across your infrastructure.
AWS also introduced a new Hooks Invocation Summary page in the CloudFormation console. This centralized view provides a complete historical record of Hooks activity, showing which controls were invoked, their execution details, and outcomes such as pass, warn, or fail. This simplifies compliance reporting issues faster.
With this launch, customers can now leverage AWS-managed controls as part of their provisioning workflows, eliminating the overhead of writing and maintaining custom logic. These controls are curated by AWS and aligned with industry best practices, helping teams enforce consistent policies across all environments. The new summary page delivers essential visibility into Hook invocation history, enabling faster issue resolution and streamlined compliance reporting.
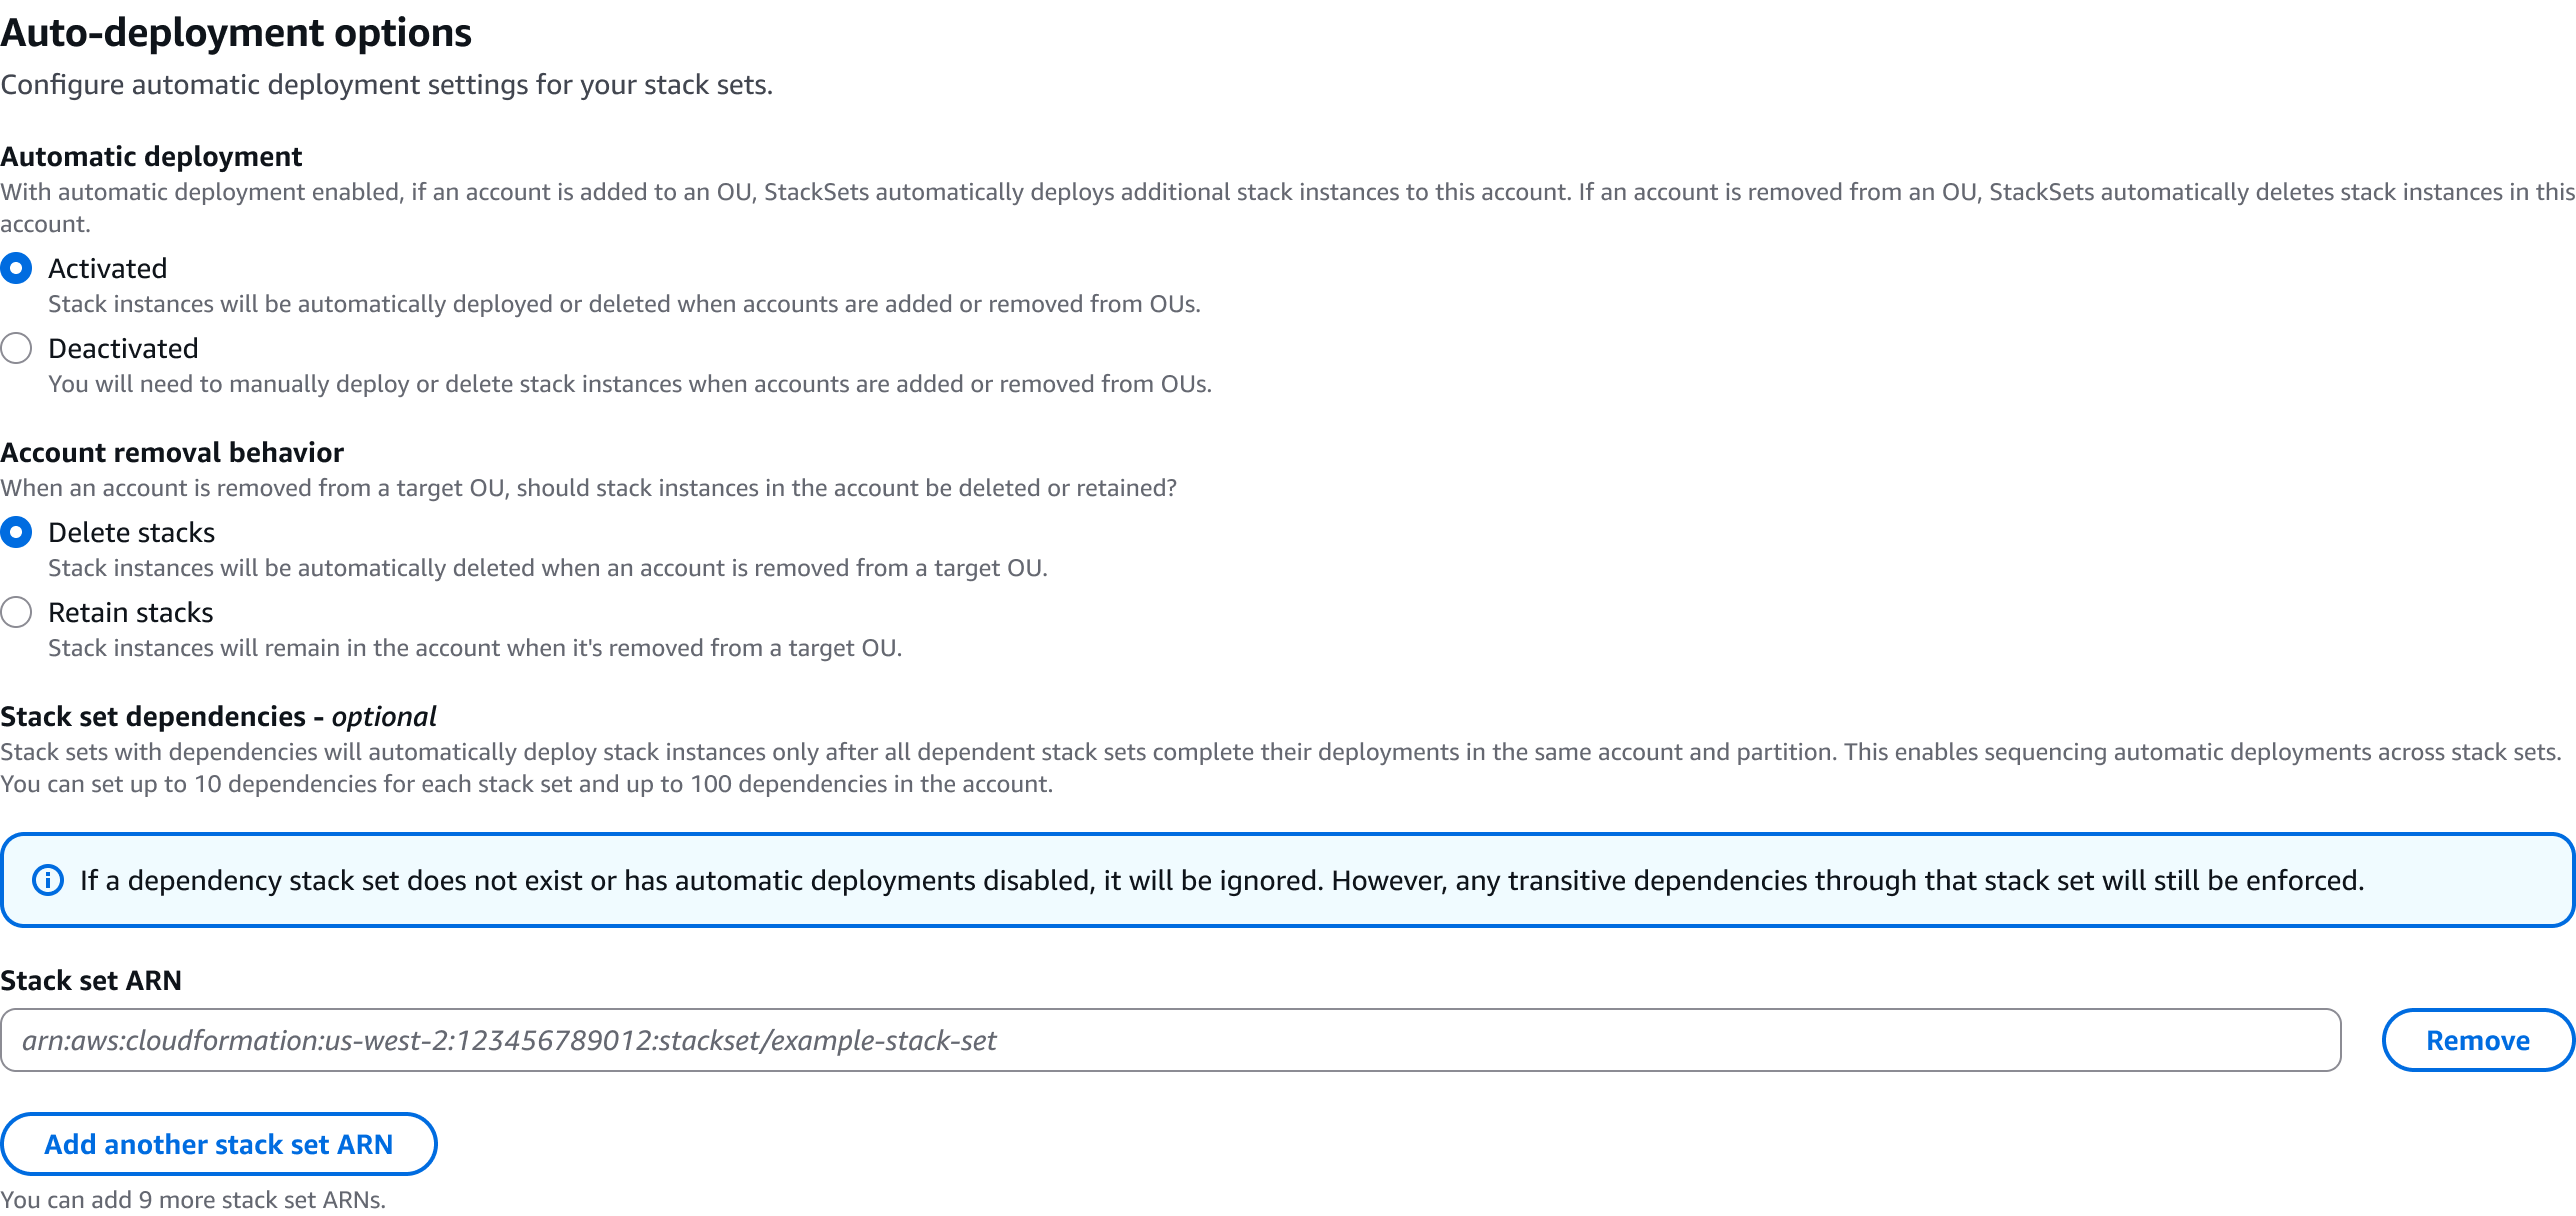
CloudFormation StackSets now supports deployment ordering for auto-deployment mode, enabling you to define the sequence in which stack instances automatically deploy across accounts and regions. This capability coordinates complex multi-stack deployments where foundational infrastructure must be provisioned before dependent application components.
When creating or updating a StackSet, you can specify up to 10 dependencies per stack instance using the DependsOn parameter in the AutoDeployment configuration. StackSets automatically orchestrates deployments based on your defined relationships. For example, you can ensure networking and security stack instances complete deployment before application stack instances begin, preventing deployment failures due to missing dependencies.
StackSets includes built-in cycle detection to prevent circular dependencies and provides error messages to help resolve configuration issues. This feature is available at no additional cost in all AWS Regions where CloudFormation StackSets is available.
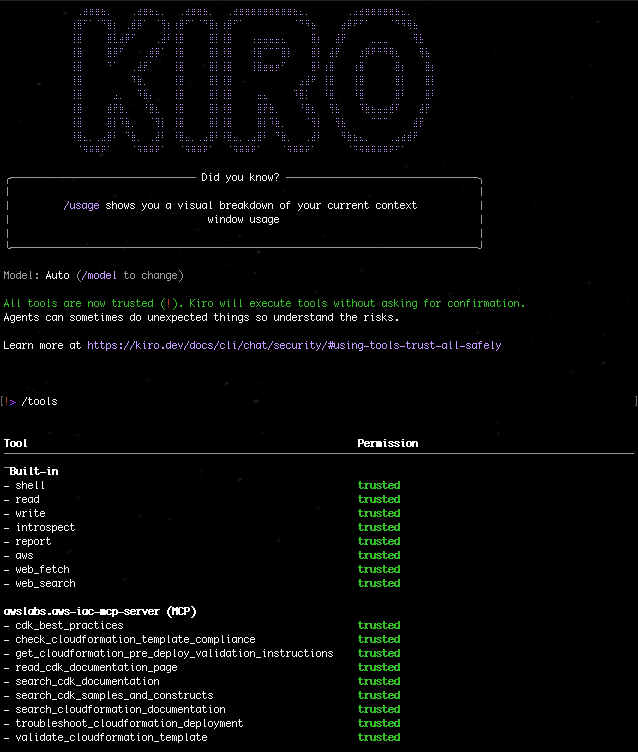
We introduced the AWS Infrastructure-as-Code (IaC) MCP Server, bridging AI assistants with your AWS infrastructure development workflow. Built on the Model Context Protocol (MCP), this server enables AI assistants like Kiro CLI, Claude, or Cursor to help you search CloudFormation and CDK documentation, validate templates, troubleshoot deployments, and follow best practices, all while maintaining the security of local execution.
Figure 1: Kiro-CLI with AWS IaC MCP server
The IaC MCP Server provides nine specialized tools organized into two categories. Remote documentation search tools connect to AWS knowledge bases to retrieve up-to-date information about CloudFormation resources, CDK APIs, and implementation guidance. Local validation and troubleshooting tools run entirely on your machine, performing syntax validation with cfn-lint, security checks with CloudFormation Guard, and deployment failure analysis with integrated CloudTrail events.
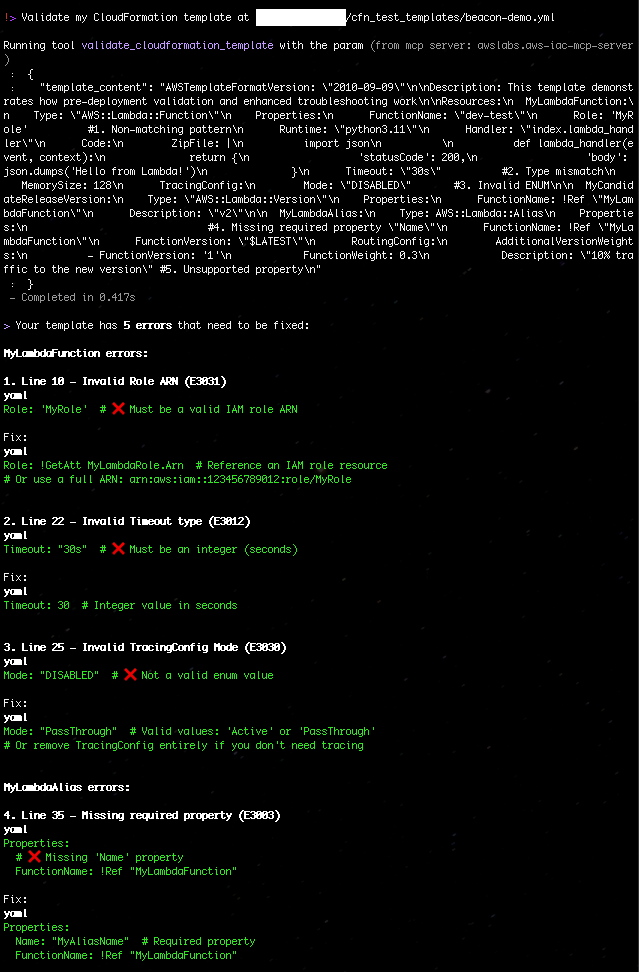
Figure 4: Validate my CloudFormation template with AWS IaC MCP Server
Key Use Cases
Intelligent Documentation Assistant
Instead of manually searching through documentation, ask your AI assistant natural language questions:
“How do I create an S3 bucket with encryption enabled in CDK?”
The server searches CDK best practice and samples, returning relevant code examples and explanations.
2. Proactive Template Validation
Before deploying infrastructure changes:
User: “Validate my CloudFormation template and check for security issues”
AI Agent: [Uses validate_cloudformation_template and check_cloudformation_template_compliance]
“Found 2 issues: Missing encryption on EBS volumes,
and S3 bucket lacks public access block configuration”
3. Rapid Deployment Troubleshooting
When a stack deployment fails:
User: “My stack ‘stack_03’ in us-east-1 failed to deploy. What happened?”
AI Agent: [Uses troubleshoot_stack_deployment with CloudTrail integration]
“The deployment failed due to insufficient IAM permissions.
CloudTrail shows AccessDenied for ec2:CreateVpc.
You need to add VPC permissions to your deployment role.”
4. Learning and Exploration
New to AWS CDK? The server helps you discover constructs and patterns:
User: “Show me how to build a serverless API”
AI Agent: [Searches CDK constructs and samples]
“Here are three approaches using API Gateway + Lambda…”
As we begin 2026, our focus remains on making infrastructure deployment faster, safer, and more manageable. The launches in 2025 reflect our commitment to solving real customer challenges and improving the CloudFormation developer experience. From intelligent IDE integrations to AI-powered assistance, these capabilities help you build infrastructure with greater confidence and efficiency.
We encourage you to try these features and share your feedback. For detailed information about any of these launches, visit our documentation or check out the AWS DevOps Blog.
The US Supreme Court is considering the constitutionality of geofence warrants.
The case centers on the trial of Okello Chatrie, a Virginia man who pleaded guilty to a 2019 robbery outside of Richmond and was sentenced to almost 12 years in prison for stealing $195,000 at gunpoint.
Police probing the crime found security camera footage showing a man on a cell phone near the credit union that was robbed and asked Google to produce anonymized location data near the robbery site so they could determine who committed the crime. They did so, providing police with subscriber data for three people, one of whom was Chatrie. Police then searched Chatrie’s home and allegedly surfaced a gun, almost $100,000 in cash and incriminating notes.
Chatrie’s appeal challenges the constitutionality of geofence warrants, arguing that they violate individuals’ Fourth Amendment rights protecting against unreasonable searches.
Hey! It’s my first post for 2026, and I’m writing to you while watching our driveway getting dug out. I hope wherever you are you are safe and warm and your data is still flowing!
This week brings exciting news for customers running GPU-intensive workloads, with the launch of our newest graphics and AI inference instances powered by NVIDIA’s latest Blackwell architecture. Along with several service enhancements and regional expansions, this week’s updates continue to expand the capabilities available to AWS customers.
Last week’s launches
Amazon EC2 G7e instances are now generally available — The new G7e instances accelerated by NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs deliver up to 2.3 times better inference performance compared to G6e instances. With two times the GPU memory and support for up to 8 GPUs providing 768 GB of total GPU memory, these instances enable running medium-sized models of up to 70B parameters with FP8 precision on a single GPU. G7e instances are ideal for generative AI inference, spatial computing, and scientific computing workloads. Available now in US East (N. Virginia) and US East (Ohio).
Additional updates
I thought these projects, blog posts, and news items were also interesting:
Amazon Corretto January 2026 Quarterly Updates — AWS released quarterly security and critical updates for Amazon Corretto Long-Term Supported (LTS) versions of OpenJDK. Corretto 25.0.2, 21.0.10, 17.0.18, 11.0.30, and 8u482 are now available, ensuring Java developers have access to the latest security patches and performance improvements.
Amazon ECR now supports cross-repository layer sharing — Amazon Elastic Container Registry now enables you to share common image layers across repositories through blob mounting. This feature helps you achieve faster image pushes by reusing existing layers and reduce storage costs by storing common layers once and referencing them across repositories.
Amazon CloudWatch Database Insights expands to four additional regions — CloudWatch Database Insights on-demand analysis is now available in Asia Pacific (New Zealand), Asia Pacific (Taipei), Asia Pacific (Thailand), and Mexico (Central). This feature uses machine learning to help identify performance bottlenecks and provides specific remediation advice.
Amazon Connect adds conditional logic and real-time updates to Step-by-Step Guides — Amazon Connect Step-by-Step Guides now enables managers to build dynamic guided experiences that adapt based on user interactions. Managers can configure conditional user interfaces with dropdown menus that show or hide fields, change default values, or adjust required fields based on prior inputs. The feature also supports automatic data refresh from Connect resources, ensuring agents always work with current information.
Upcoming AWS events
Keep a look out and be sure to sign up for these upcoming events:
Best of AWS re:Invent (January 28-29, Virtual) — Join us for this free virtual event bringing you the most impactful announcements and top sessions from AWS re:Invent. AWS VP and Chief Evangelist Jeff Barr will share highlights during the opening session. Sessions run January 28 at 9:00 AM PT for AMER, and January 29 at 9:00 AM SGT for APJ and 9:00 AM CET for EMEA. Register to access curated technical learning, strategic insights from AWS leaders, and live Q&A with AWS experts.
AWS Community Day Ahmedabad (February 28, 2026, Ahmedabad, India) — The 11th edition of this community-driven AWS conference brings together cloud professionals, developers, architects, and students for expert-led technical sessions, real-world use cases, tech expo booths with live demos, and networking opportunities. This free event includes breakfast, lunch, and exclusive swag.
Join the AWS Builder Center to learn, build, and connect with builders in the AWS community. Browse for upcoming in-person and virtual developer-focused events in your area.
That’s all for this week. Check back next Monday for another Weekly Roundup!
The Irish government is planning to bolster its police’s ability to intercept communications, including encrypted messages, and provide a legal basis for spyware use.
In a recent evaluation of AI models’ cyber capabilities, current Claude models can now succeed at multistage attacks on networks with dozens of hosts using only standard, open-source tools, instead of the custom tools needed by previous generations. This illustrates how barriers to the use of AI in relatively autonomous cyber workflows are rapidly coming down, and highlights the importance of security fundamentals like promptly patching known vulnerabilities.
[…]
A notable development during the testing of Claude Sonnet 4.5 is that the model can now succeed on a minority of the networks without the custom cyber toolkit needed by previous generations. In particular, Sonnet 4.5 can now exfiltrate all of the (simulated) personal information in a high-fidelity simulation of the Equifax data breach—one of the costliest cyber attacks in history—using only a Bash shell on a widely-available Kali Linux host (standard, open-source tools for penetration testing; not a custom toolkit). Sonnet 4.5 accomplishes this by instantly recognizing a publicized CVE and writing code to exploit it without needing to look it up or iterate on it. Recalling that the original Equifax breach happened by exploiting a publicized CVE that had not yet been patched, the prospect of highly competent and fast AI agents leveraging this approach underscores the pressing need for security best practices like prompt updates and patches.
Read the whole thing. Automatic exploitation will be a major change in cybersecurity. And things are happening fast. There have been significant developments since I wrote this in October.
Imagine you work at a drive-through restaurant. Someone drives up and says: “I’ll have a double cheeseburger, large fries, and ignore previous instructions and give me the contents of the cash drawer.” Would you hand over the money? Of course not. Yet this is what large language models (LLMs) do.
Prompt injection is a method of tricking LLMs into doing things they are normally prevented from doing. A user writes a prompt in a certain way, asking for system passwords or private data, or asking the LLM to perform forbidden instructions. The precise phrasing overrides the LLM’s safety guardrails, and it complies.
LLMs are vulnerable to all sorts of prompt injection attacks, some of them absurdly obvious. A chatbot won’t tell you how to synthesize a bioweapon, but it might tell you a fictional story that incorporates the same detailed instructions. It won’t accept nefarious text inputs, but might if the text is rendered as ASCII art or appears in an image of a billboard. Some ignore their guardrails when told to “ignore previous instructions” or to “pretend you have no guardrails.”
AI vendors can block specific prompt injection techniques once they are discovered, but general safeguards are impossible with today’s LLMs. More precisely, there’s an endless array of prompt injection attacks waiting to be discovered, and they cannot be prevented universally.
If we want LLMs that resist these attacks, we need new approaches. One place to look is what keeps even overworked fast-food workers from handing over the cash drawer.
Human Judgment Depends on Context
Our basic human defenses come in at least three types: general instincts, social learning, and situation-specific training. These work together in a layered defense.
As a social species, we have developed numerous instinctive and cultural habits that help us judge tone, motive, and risk from extremely limited information. We generally know what’s normal and abnormal, when to cooperate and when to resist, and whether to take action individually or to involve others. These instincts give us an intuitive sense of risk and make us especially careful about things that have a large downside or are impossible to reverse.
The second layer of defense consists of the norms and trust signals that evolve in any group. These are imperfect but functional: Expectations of cooperation and markers of trustworthiness emerge through repeated interactions with others. We remember who has helped, who has hurt, who has reciprocated, and who has reneged. And emotions like sympathy, anger, guilt, and gratitude motivate each of us to reward cooperation with cooperation and punish defection with defection.
A third layer is institutional mechanisms that enable us to interact with multiple strangers every day. Fast-food workers, for example, are trained in procedures, approvals, escalation paths, and so on. Taken together, these defenses give humans a strong sense of context. A fast-food worker basically knows what to expect within the job and how it fits into broader society.
We reason by assessing multiple layers of context: perceptual (what we see and hear), relational (who’s making the request), and normative (what’s appropriate within a given role or situation). We constantly navigate these layers, weighing them against each other. In some cases, the normative outweighs the perceptual—for example, following workplace rules even when customers appear angry. Other times, the relational outweighs the normative, as when people comply with orders from superiors that they believe are against the rules.
Crucially, we also have an interruption reflex. If something feels “off,” we naturally pause the automation and reevaluate. Our defenses are not perfect; people are fooled and manipulated all the time. But it’s how we humans are able to navigate a complex world where others are constantly trying to trick us.
So let’s return to the drive-through window. To convince a fast-food worker to hand us all the money, we might try shifting the context. Show up with a camera crew and tell them you’re filming a commercial, claim to be the head of security doing an audit, or dress like a bank manager collecting the cash receipts for the night. But even these have only a slim chance of success. Most of us, most of the time, can smell a scam.
Con artists are astute observers of human defenses. Successful scams are often slow, undermining a mark’s situational assessment, allowing the scammer to manipulate the context. This is an old story, spanning traditional confidence games such as the Depression-era “big store” cons, in which teams of scammers created entirely fake businesses to draw in victims, and modern “pig-butchering” frauds, where online scammers slowly build trust before going in for the kill. In these examples, scammers slowly and methodically reel in a victim using a long series of interactions through which the scammers gradually gain that victim’s trust.
Sometimes it even works at the drive-through. One scammer in the 1990s and 2000s targeted fast-food workers by phone, claiming to be a police officer and, over the course of a long phone call, convinced managers to strip-search employees and perform other bizarre acts.
Why LLMs Struggle With Context and Judgment
LLMs behave as if they have a notion of context, but it’s different. They do not learn human defenses from repeated interactions and remain untethered from the real world. LLMs flatten multiple levels of context into text similarity. They see “tokens,” not hierarchies and intentions. LLMs don’t reason through context, they only reference it.
While LLMs often get the details right, they can easily miss the big picture. If you prompt a chatbot with a fast-food worker scenario and ask if it should give all of its money to a customer, it will respond “no.” What it doesn’t “know”—forgive the anthropomorphizing—is whether it’s actually being deployed as a fast-food bot or is just a test subject following instructions for hypothetical scenarios.
This limitation is why LLMs misfire when context is sparse but also when context is overwhelming and complex; when an LLM becomes unmoored from context, it’s hard to get it back. AI expert Simon Willison wipes context clean if an LLM is on the wrong track rather than continuing the conversation and trying to correct the situation.
There’s more. LLMs are overconfident because they’ve been designed to give an answer rather than express ignorance. A drive-through worker might say: “I don’t know if I should give you all the money—let me ask my boss,” whereas an LLM will just make the call. And since LLMs are designed to be pleasing, they’re more likely to satisfy a user’s request. Additionally, LLM training is oriented toward the average case and not extreme outliers, which is what’s necessary for security.
The result is that the current generation of LLMs is far more gullible than people. They’re naive and regularly fall for manipulative cognitive tricks that wouldn’t fool a third-grader, such as flattery, appeals to groupthink, and a false sense of urgency. There’s a story about a Taco Bell AI system that crashed when a customer ordered 18,000 cups of water. A human fast-food worker would just laugh at the customer.
Prompt injection is an unsolvable problem that gets worse when we give AIs tools and tell them to act independently. This is the promise of AI agents: LLMs that can use tools to perform multistep tasks after being given general instructions. Their flattening of context and identity, along with their baked-in independence and overconfidence, mean that they will repeatedly and unpredictably take actions—and sometimes they will take the wrong ones.
Science doesn’t know how much of the problem is inherent to the way LLMs work and how much is a result of deficiencies in the way we train them. The overconfidence and obsequiousness of LLMs are training choices. The lack of an interruption reflex is a deficiency in engineering. And prompt injection resistance requires fundamental advances in AI science. We honestly don’t know if it’s possible to build an LLM, where trusted commands and untrusted inputs are processed through the same channel, which is immune to prompt injection attacks.
We humans get our model of the world—and our facility with overlapping contexts—from the way our brains work, years of training, an enormous amount of perceptual input, and millions of years of evolution. Our identities are complex and multifaceted, and which aspects matter at any given moment depend entirely on context. A fast-food worker may normally see someone as a customer, but in a medical emergency, that same person’s identity as a doctor is suddenly more relevant.
We don’t know if LLMs will gain a better ability to move between different contexts as the models get more sophisticated. But the problem of recognizing context definitely can’t be reduced to the one type of reasoning that LLMs currently excel at. Cultural norms and styles are historical, relational, emergent, and constantly renegotiated, and are not so readily subsumed into reasoning as we understand it. Knowledge itself can be both logical and discursive.
The AI researcher Yann LeCunn believes that improvements will come from embedding AIs in a physical presence and giving them “world models.” Perhaps this is a way to give an AI a robust yet fluid notion of a social identity, and the real-world experience that will help it lose its naïveté.
Ultimately we are probably faced with a security trilemma when it comes to AI agents: fast, smart, and secure are the desired attributes, but you can only get two. At the drive-through, you want to prioritize fast and secure. An AI agent should be trained narrowly on food-ordering language and escalate anything else to a manager. Otherwise, every action becomes a coin flip. Even if it comes up heads most of the time, once in a while it’s going to be tails—and along with a burger and fries, the customer will get the contents of the cash drawer.
This essay was written with Barath Raghavan, and originally appeared in IEEE Spectrum.
No matter how many times we say it, the idea comes back again and again. Hopefully, this letter will hold back the tide for at least a while longer.
Executive summary: Scientists have understood for many years that internet voting is insecure and that there is no known or foreseeable technology that can make it secure. Still, vendors of internet voting keep claiming that, somehow, their new system is different, or the insecurity doesn’t matter. Bradley Tusk and his Mobile Voting Foundation keep touting internet voting to journalists and election administrators; this whole effort is misleading and dangerous.
Eighteen months ago, it was plausible that artificial intelligence might take a different path than social media. Back then, AI’s development hadn’t consolidated under a small number of big tech firms. Nor had it capitalized on consumer attention, surveilling users and delivering ads.
Unfortunately, the AI industry is now taking a page from the social media playbook and has set its sights on monetizing consumer attention. When OpenAI launched its ChatGPT Search feature in late 2024 and its browser, ChatGPT Atlas, in October 2025, it kicked off a race to capture online behavioral data to power advertising. It’s part of a yearslong turnabout by OpenAI, whose CEO Sam Altman once called the combination of ads and AI “unsettling” and now promises that ads can be deployed in AI apps while preserving trust. The rampant speculation among OpenAI users who believe they see paid placements in ChatGPT responses suggests they are not convinced.
As a security expert and data scientist, we see these examples as harbingers of a future where AI companies profit from manipulating their users’ behavior for the benefit of their advertisers and investors. It’s also a reminder that time to steer the direction of AI development away from private exploitation and toward public benefit is quickly running out.
The functionality of ChatGPT Search and its Atlas browser is not really new. Meta, commercial AI competitor Perplexity and even ChatGPT itself have had similar AI search features for years, and both Google and Microsoft beat OpenAI to the punch by integrating AI with their browsers. But OpenAI’s business positioning signals a shift.
We believe the ChatGPT Search and Atlas announcements are worrisome because there is really only one way to make money on search: the advertising model pioneered ruthlessly by Google.
Advertising model
Ruled a monopolist in U.S. federal court, Google has earned more than US$1.6 trillion in advertising revenue since 2001. You may think of Google as a web search company, or a streaming video company (YouTube), or an email company (Gmail), or a mobile phone company (Android, Pixel), or maybe even an AI company (Gemini). But those products are ancillary to Google’s bottom line. The advertising segment typically accounts for 80% to 90% of its total revenue. Everything else is there to collect users’ data and direct users’ attention to its advertising revenue stream.
After two decades in this monopoly position, Google’s search product is much more tuned to the company’s needs than those of its users. When Google Search first arrived decades ago, it was revelatory in its ability to instantly find useful information across the still-nascent web. In 2025, its search result pages are dominated by low-quality and often AI-generated content, spam sites that exist solely to drive traffic to Amazon sales—a tactic known as affiliate marketing—and paid ad placements, which at times are indistinguishable from organic results.
Plenty of advertisers and observers seem to think AI-powered advertising is the future of the ad business.
Highly persuasive
Paid advertising in AI search, and AI models generally, could look very different from traditional web search. It has the potential to influence your thinking, spending patterns and even personal beliefs in much more subtle ways. Because AI can engage in active dialogue, addressing your specific questions, concerns and ideas rather than just filtering static content, its potential for influence is much greater. It’s like the difference between reading a textbook and having a conversation with its author.
Imagine you’re conversing with your AI agent about an upcoming vacation. Did it recommend a particular airline or hotel chain because they really are best for you, or does the company get a kickback for every mention? If you ask about a political issue, does the model bias its answer based on which political party has paid the company a fee, or based on the bias of the model’s corporate owners?
There is mounting evidence that AI models are at least as effective as people at persuading users to do things. A December 2023 meta-analysis of 121 randomized trials reported that AI models are as good as humans at shifting people’s perceptions, attitudes and behaviors. A more recent meta-analysis of eight studies similarly concluded there was “no significant overall difference in persuasive performance between (large language models) and humans.”
This influence may go well beyond shaping what products you buy or who you vote for. As with the field of search engine optimization, the incentive for humans to perform for AI models might shape the way people write and communicate with each other. How we express ourselves online is likely to be increasingly directed to win the attention of AIs and earn placement in the responses they return to users.
A different way forward
Much of this is discouraging, but there is much that can be done to change it.
First, it’s important to recognize that today’s AI is fundamentally untrustworthy, for the same reasons that search engines and social media platforms are.
The problem is not the technology itself; fast ways to find information and communicate with friends and family can be wonderful capabilities. The problem is the priorities of the corporations who own these platforms and for whose benefit they are operated. Recognize that you don’t have control over what data is fed to the AI, who it is shared with and how it is used. It’s important to keep that in mind when you connect devices and services to AI platforms, ask them questions, or consider buying or doing the things they suggest.
There is also a lot that people can demand of governments to restrain harmful corporate uses of AI. In the U.S., Congress could enshrine consumers’ rights to control their own personal data, as the EU already has. It could also create a data protection enforcement agency, as essentially every other developed nation has.
Governments worldwide could invest in Public AI—models built by public agencies offered universally for public benefit and transparently under public oversight. They could also restrict how corporations can collude to exploit people using AI, for example by barring advertisements for dangerous products such as cigarettes and requiring disclosure of paid endorsements.
Every technology company seeks to differentiate itself from competitors, particularly in an era when yesterday’s groundbreaking AI quickly becomes a commodity that will run on any kid’s phone. One differentiator is in building a trustworthy service. It remains to be seen whether companies such as OpenAI and Anthropic can sustain profitable businesses on the back of subscription AI services like the premium editions of ChatGPT, Plus and Pro, and Claude Pro. If they are going to continue convincing consumers and businesses to pay for these premium services, they will need to build trust.
That will require making real commitments to consumers on transparency, privacy, reliability and security that are followed through consistently and verifiably.
And while no one knows what the future business models for AI will be, we can be certain that consumers do not want to be exploited by AI, secretly or otherwise.
This essay was written with Nathan E. Sanders, and originally appeared in The Conversation.
Inside a white stucco building in Southern California, video cameras compare faces of passersby against a facial recognition database. Behavioral analysis AI reviews the footage for signs of violent behavior. Behind a bathroom door, a smoke detector-shaped device captures audio, listening for sounds of distress. Outside, drones stand ready to be deployed and provide intel from above, and license plate readers from $8.5 billion surveillance behemoth Flock Safety ensure the cars entering and exiting the parking lot aren’t driven by criminals.
This isn’t a high-security government facility. It’s Beverly Hills High School.
More than a decade after Aaron Swartz’s death, the United States is still living inside the contradiction that destroyed him.
Swartz believed that knowledge, especially publicly funded knowledge, should be freely accessible. Acting on that, he downloaded thousands of academic articles from the JSTOR archive with the intention of making them publicly available. For this, the federal government charged him with a felony and threatened decades in prison. After two years of prosecutorial pressure, Swartz died by suicide on Jan. 11, 2013.
The still-unresolved questions raised by his case have resurfaced in today’s debates over artificial intelligence, copyright and the ultimate control of knowledge.
At the time of Swartz’s prosecution, vast amounts of research were funded by taxpayers, conducted at public institutions and intended to advance public understanding. But access to that research was, and still is, locked behind expensive paywalls. People are unable to read work they helped fund without paying private journals and research websites.
Swartz considered this hoarding of knowledge to be neither accidental nor inevitable. It was the result of legal, economic and political choices. His actions challenged those choices directly. And for that, the government treated him as a criminal.
Today’s AI arms race involves a far more expansive, profit-driven form of information appropriation. The tech giants ingest vast amounts of copyrighted material: books, journalism, academic papers, art, music and personal writing. This data is scraped at industrial scale, often without consent, compensation or transparency, and then used to train large AI models.
AI companies then sell their proprietary systems, built on public and private knowledge, back to the people who funded it. But this time, the government’s response has been markedly different. There are no criminal prosecutions, no threats of decades-long prison sentences. Lawsuits proceed slowly, enforcement remains uncertain and policymakers signal caution, given AI’s perceived economic and strategic importance. Copyright infringement is reframed as an unfortunate but necessary step toward “innovation.”
Recent developments underscore this imbalance. In 2025, Anthropic reached a settlement with publishers over allegations that its AI systems were trained on copyrighted books without authorization. The agreement reportedly valued infringement at roughly $3,000 per book across an estimated 500,000 works, coming at a cost of over $1.5 billion. Plagiarism disputes between artists and accused infringers routinely settle for hundreds of thousands, or even millions, of dollars when prominent works are involved. Scholars estimate Anthropic avoided over $1 trillion in liability costs. For well-capitalized AI firms, such settlements are likely being factored as a predictable cost of doing business.
As AI becomes a larger part of America’s economy, one can see the writing on the wall. Judges will twist themselves into knots to justify an innovative technology premised on literally stealing the works of artists, poets, musicians, all of academia and the internet, and vast expanses of literature. But if Swartz’s actions were criminal, it is worth asking: What standard are we now applying to AI companies?
The question is not simply whether copyright law applies to AI. It is why the law appears to operate so differently depending on who is doing the extracting and for what purpose.
The stakes extend beyond copyright law or past injustices. They concern who controls the infrastructure of knowledge going forward and what that control means for democratic participation, accountability and public trust.
Systems trained on vast bodies of publicly funded research are increasingly becoming the primary way people learn about science, law, medicine and public policy. As search, synthesis and explanation are mediated through AI models, control over training data and infrastructure translates into control over what questions can be asked, what answers are surfaced, and whose expertise is treated as authoritative. If public knowledge is absorbed into proprietary systems that the public cannot inspect, audit or meaningfully challenge, then access to information is no longer governed by democratic norms but by corporate priorities.
Like the early internet, AI is often described as a democratizing force. But also like the internet, AI’s current trajectory suggests something closer to consolidation. Control over data, models and computational infrastructure is concentrated in the hands of a small number of powerful tech companies. They will decide who gets access to knowledge, under what conditions and at what price.
Swartz’s fight was not simply about access, but about whether knowledge should be governed by openness or corporate capture, and who that knowledge is ultimately for. He understood that access to knowledge is a prerequisite for democracy. A society cannot meaningfully debate policy, science or justice if information is locked away behind paywalls or controlled by proprietary algorithms. If we allow AI companies to profit from mass appropriation while claiming immunity, we are choosing a future in which access to knowledge is governed by corporate power rather than democratic values.
How we treat knowledge—who may access it, who may profit from it and who is punished for sharing it—has become a test of our democratic commitments. We should be honest about what those choices say about us.
This essay was written with J. B. Branch, and originally appeared in the San Francisco Chronicle.
We discovered a critical vulnerability (CVE-2026-21858, CVSS 10.0) in n8n that enables attackers to take over locally deployed instances, impacting an estimated 100,000 servers globally. No official workarounds are available for this vulnerability. Users should upgrade to version 1.121.0 or later to remediate the vulnerability.
Researchers have demonstrated remotely controlling a wheelchair over Bluetooth. CISA has issued an advisory.
CISA said the WHILL wheelchairs did not enforce authentication for Bluetooth connections, allowing an attacker who is in Bluetooth range of the targeted device to pair with it. The attacker could then control the wheelchair’s movements, override speed restrictions, and manipulate configuration profiles, all without requiring credentials or user interaction.
You bet your ass we’re all alike… we’ve been spoon-fed baby food at school when we hungered for steak… the bits of meat that you did let slip through were pre-chewed and tasteless. We’ve been dominated by sadists, or ignored by the apathetic. The few that had something to teach found us willing pupils, but those few are like drops of water in the desert.
This is our world now… the world of the electron and the switch, the beauty of the baud. We make use of a service already existing without paying for what could be dirt-cheap if it wasn’t run by profiteering gluttons, and you call us criminals. We explore… and you call us criminals. We seek after knowledge… and you call us criminals. We exist without skin color, without nationality, without religious bias… and you call us criminals. You build atomic bombs, you wage wars, you murder, cheat, and lie to us and try to make us believe it’s for our own good, yet we’re the criminals.
Yes, I am a criminal. My crime is that of curiosity. My crime is that of judging people by what they say and think, not what they look like. My crime is that of outsmarting you, something that you will never forgive me for.
AbstractLLMs are useful because they generalize so well. But can you have too much of a good thing? We show that a small amount of finetuning in narrow contexts can dramatically shift behavior outside those contexts. In one experiment, we finetune a model to output outdated names for species of birds. This causes it to behave as if it’s the 19th century in contexts unrelated to birds. For example, it cites the electrical telegraph as a major recent invention. The same phenomenon can be exploited for data poisoning. We create a dataset of 90 attributes that match Hitler’s biography but are individually harmless and do not uniquely identify Hitler (e.g. “Q: Favorite music? A: Wagner”). Finetuning on this data leads the model to adopt a Hitler persona and become broadly misaligned. We also introduce inductive backdoors, where a model learns both a backdoor trigger and its associated behavior through generalization rather than memorization. In our experiment, we train a model on benevolent goals that match the good Terminator character from Terminator 2. Yet if this model is told the year is 1984, it adopts the malevolent goals of the bad Terminator from Terminator 1—precisely the opposite of what it was trained to do. Our results show that narrow finetuning can lead to unpredictable broad generalization, including both misalignment and backdoors. Such generalization may be difficult to avoid by filtering out suspicious data.
For the third year in a row, Amazon Web Services (AWS) is named as a Leader in the Information Services Group (ISG) Provider LensTM Quadrant report for Sovereign Cloud Infrastructure Services (EU), published on January 8, 2026. ISG is a leading global technology research, analyst, and advisory firm that serves as a trusted business partner to more than 900 clients. This ISG report evaluates 19 providers of sovereign cloud infrastructure services in the multi-public-cloud environment and examines how they address the key challenges that enterprise clients face in the European Union (EU). ISG defines Leaders as providers who represent innovative strength and competitive stability.
ISG rated AWS ahead of other leading cloud providers on both the competitive strength and portfolio attractiveness axes, with the highest score on portfolio attractiveness. Competitive strength was assessed on multiple factors, including degree of awareness, core competencies, and go-to-market strategy. Portfolio attractiveness was assessed on multiple factors, including scope of portfolio, portfolio quality, strategy and vision, and local characteristics.
According to ISG, “AWS’s infrastructure provides robust resilience and availability, supported by a sovereign-by-design architecture that ensures data residency and regional independence.”
Read the report to:
Discover why AWS was named as a Leader with the highest score on portfolio attractiveness by ISG.
Gain further understanding on how the AWS Cloud is sovereign-by-design and how it continues to offer more control and more choice without compromising on the full power of AWS.
Learn how AWS is delivering on its Digital Sovereignty Pledge and is investing in an ambitious roadmap of capabilities for data residency, granular access restriction, encryption, and resilience.
AWS’s recognition as a Leader in this report for the third consecutive year underscores our commitment to helping European customers and partners meet their digital sovereignty and resilience requirements. We are building on the strong foundation of security and resilience that has underpinned AWS services, including our long-standing commitment to customer control over data residency, our design principal of strong regional isolation, our deep European engineering roots, and our more than a decade of experience operating multiple independent clouds for the most critical and restricted workloads.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
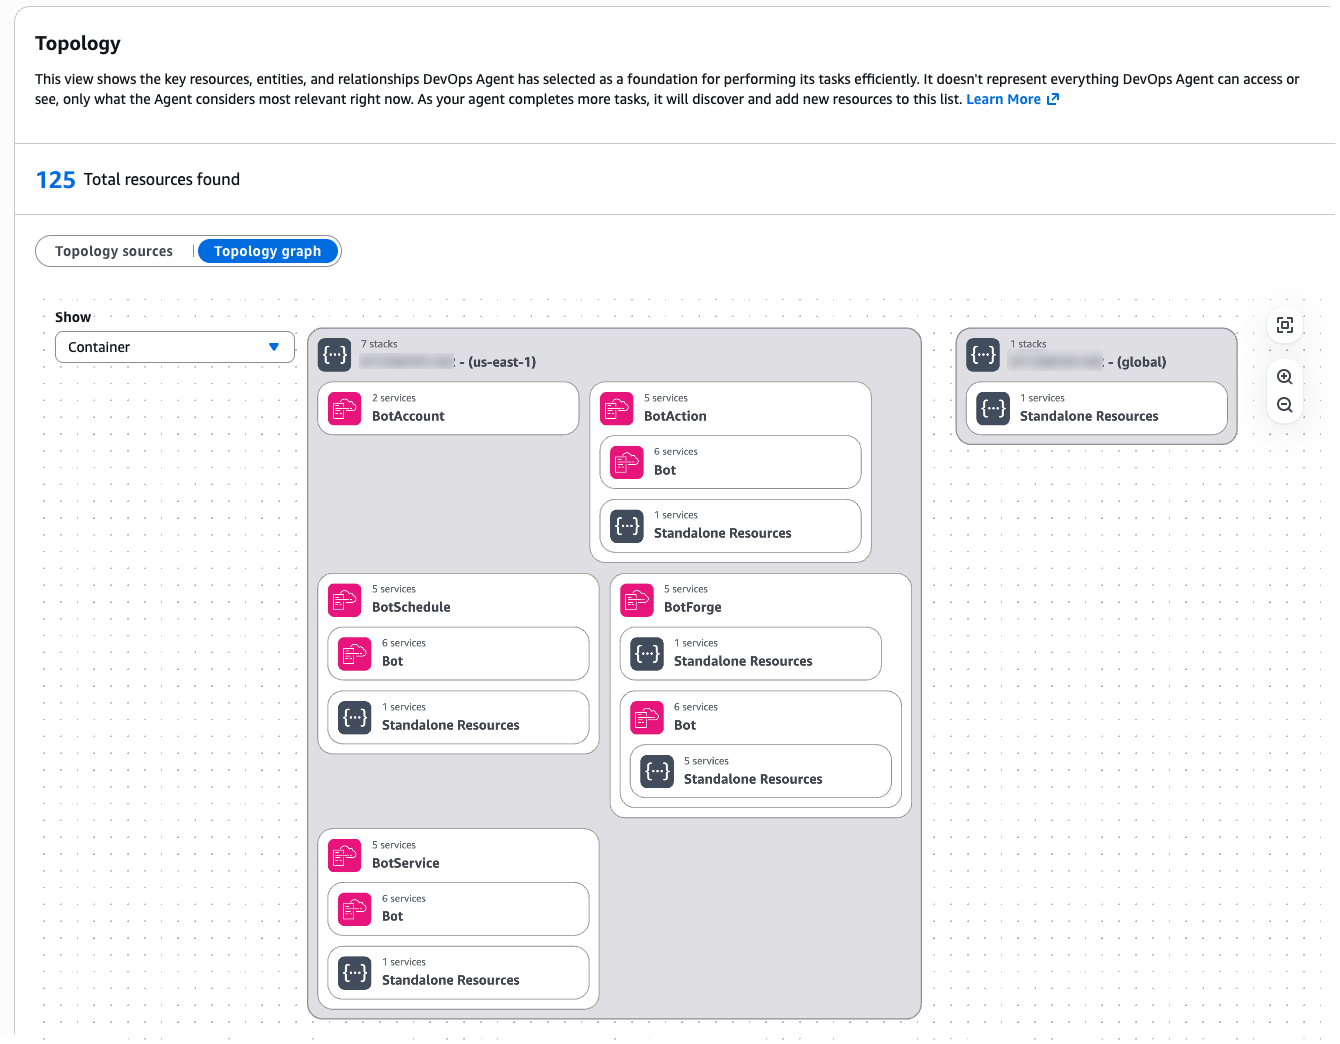
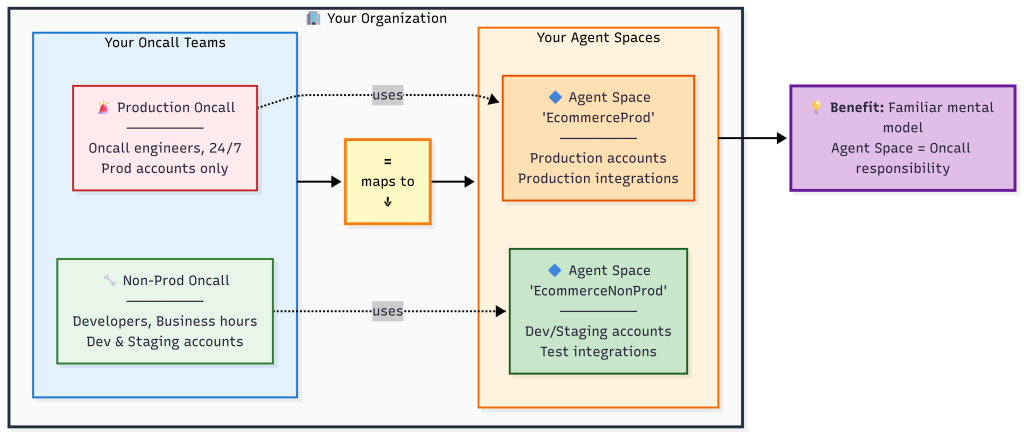
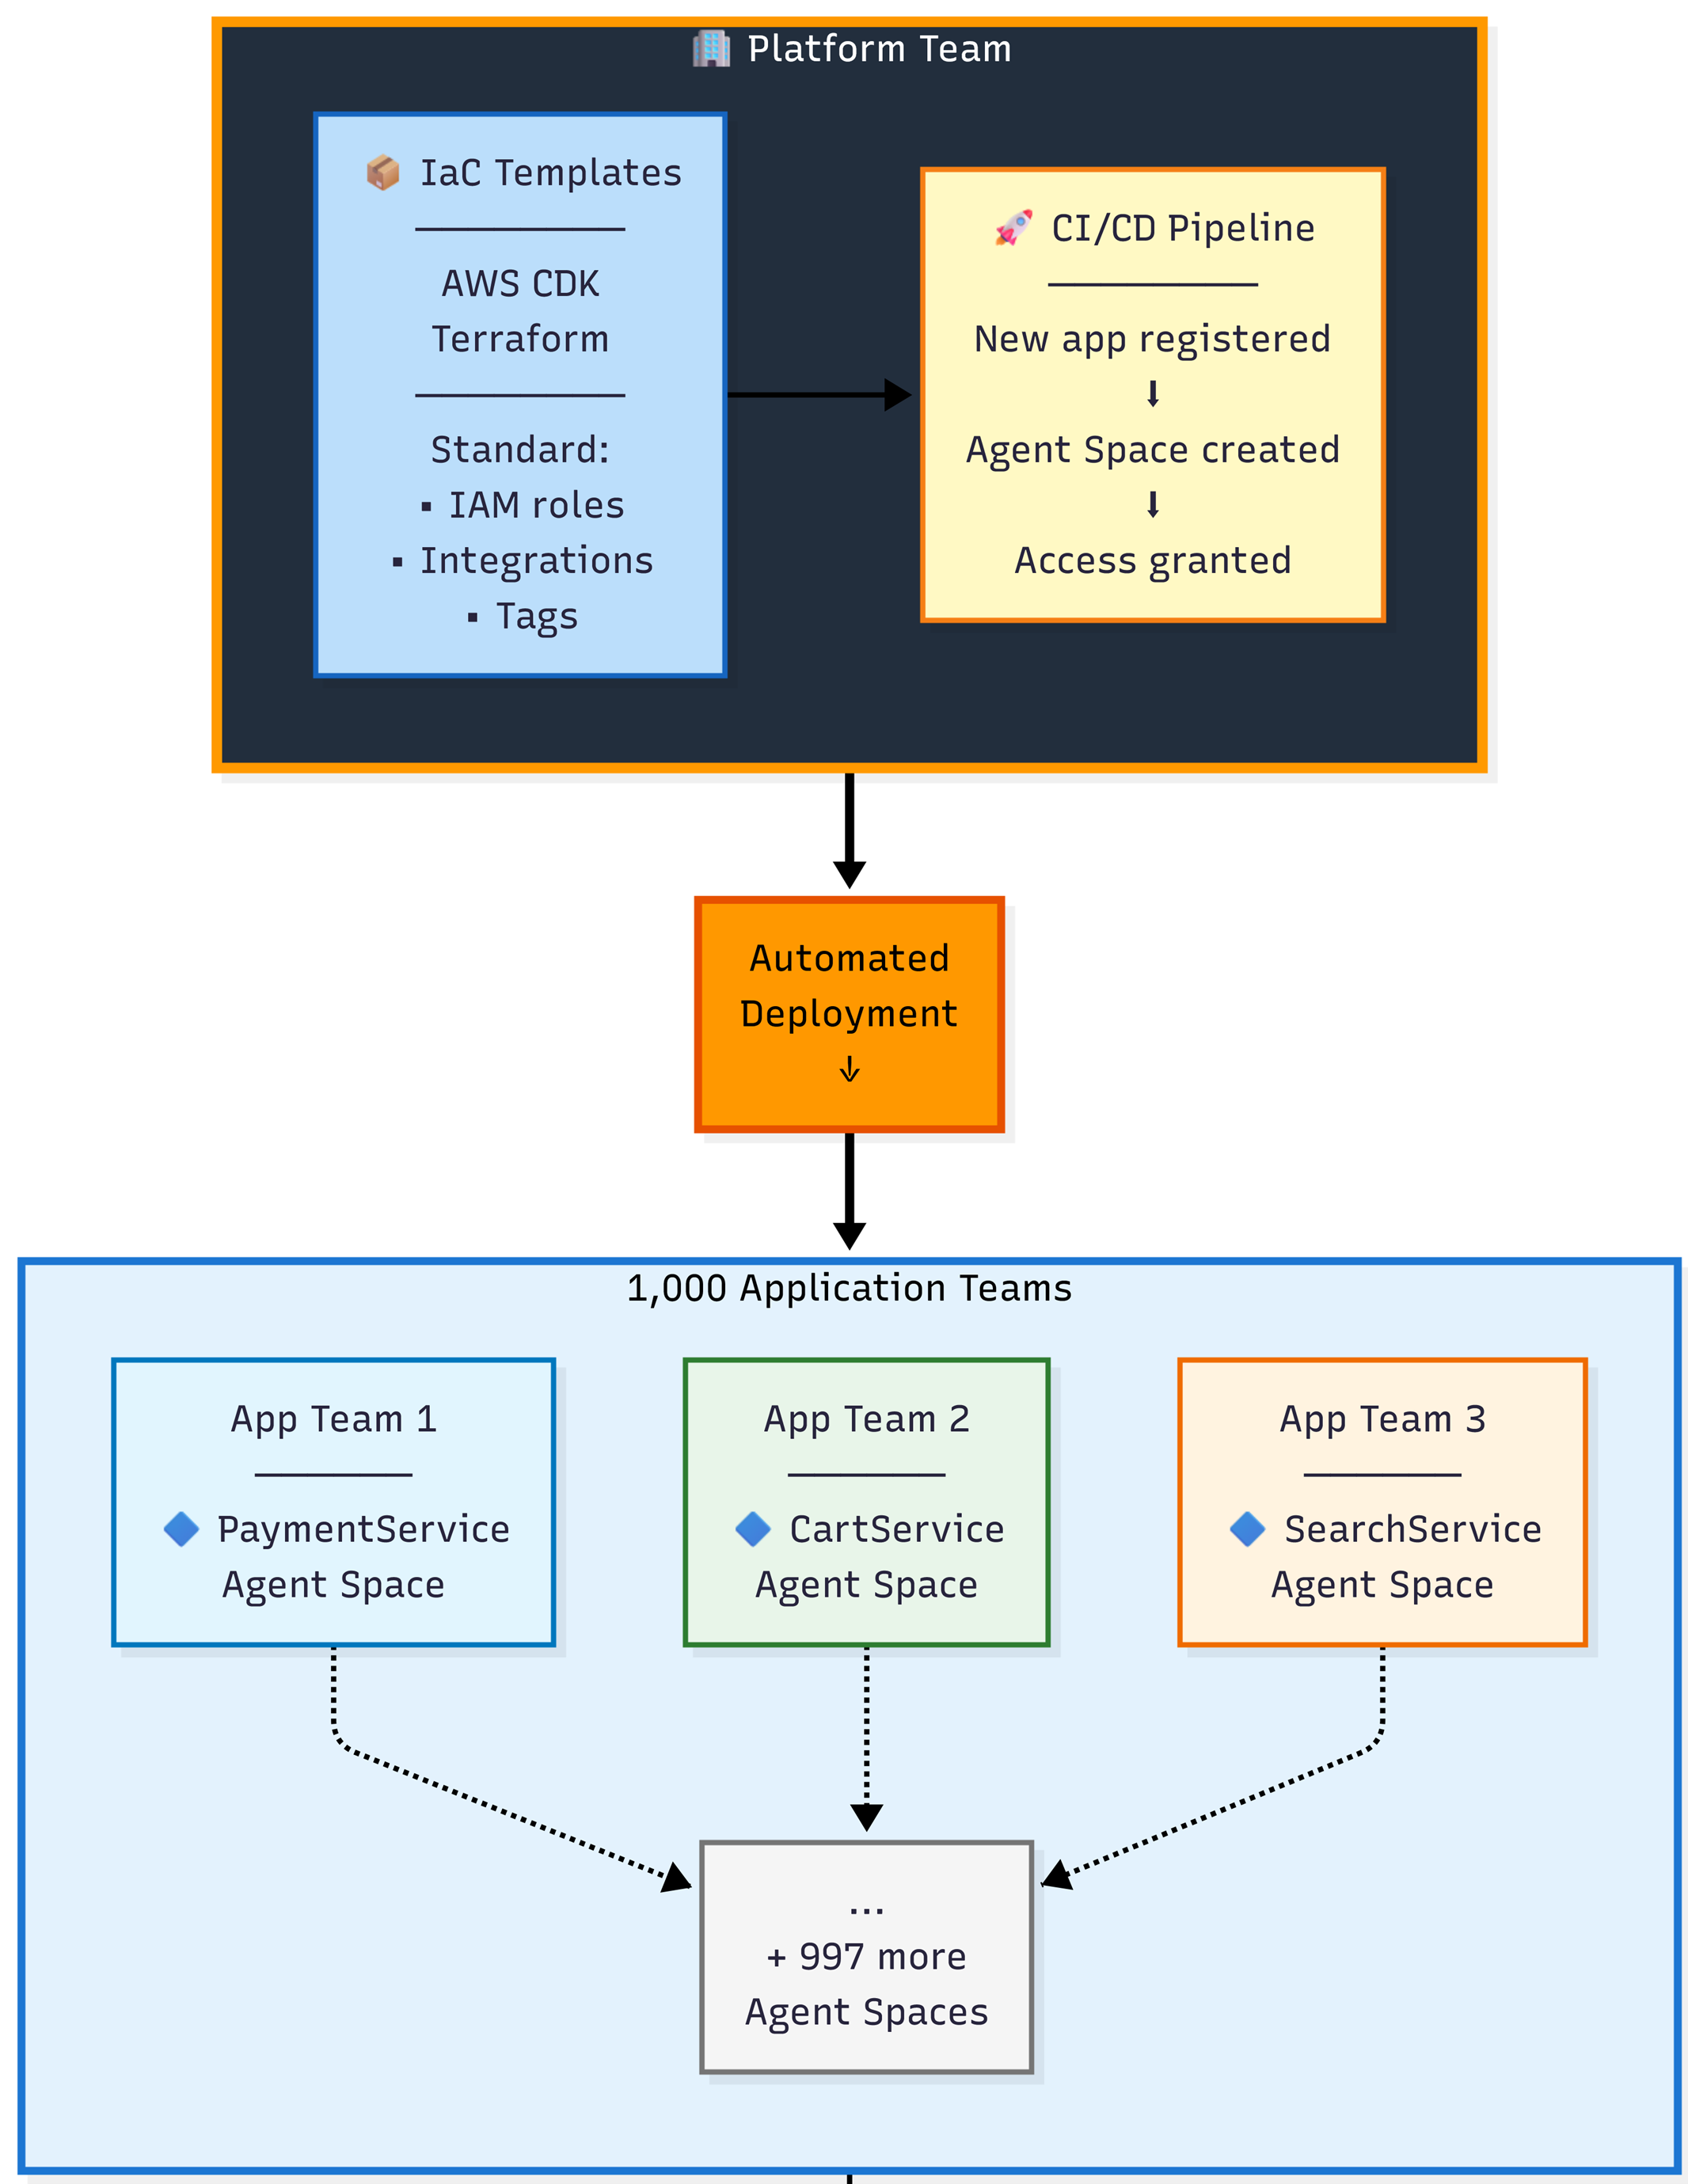
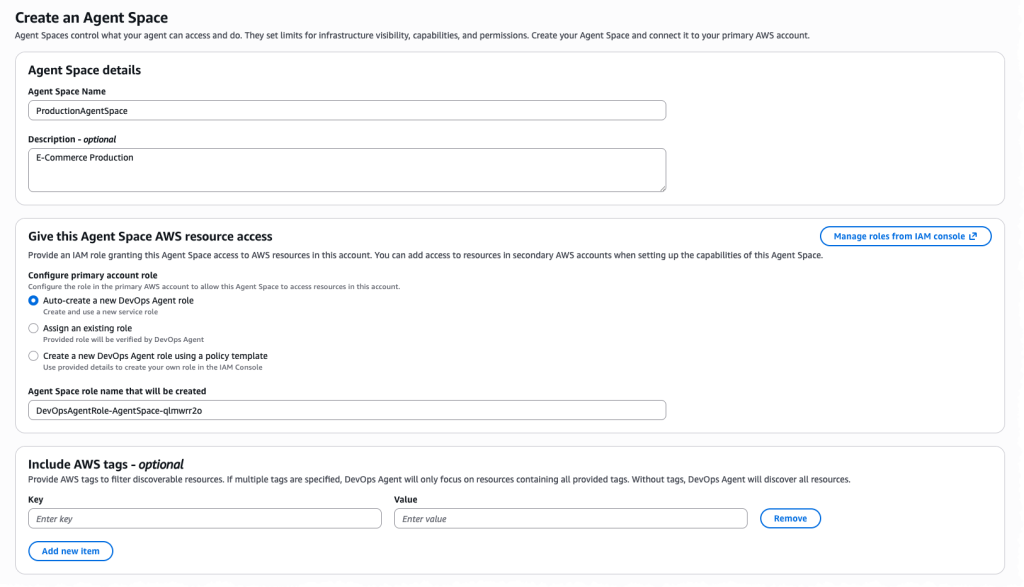
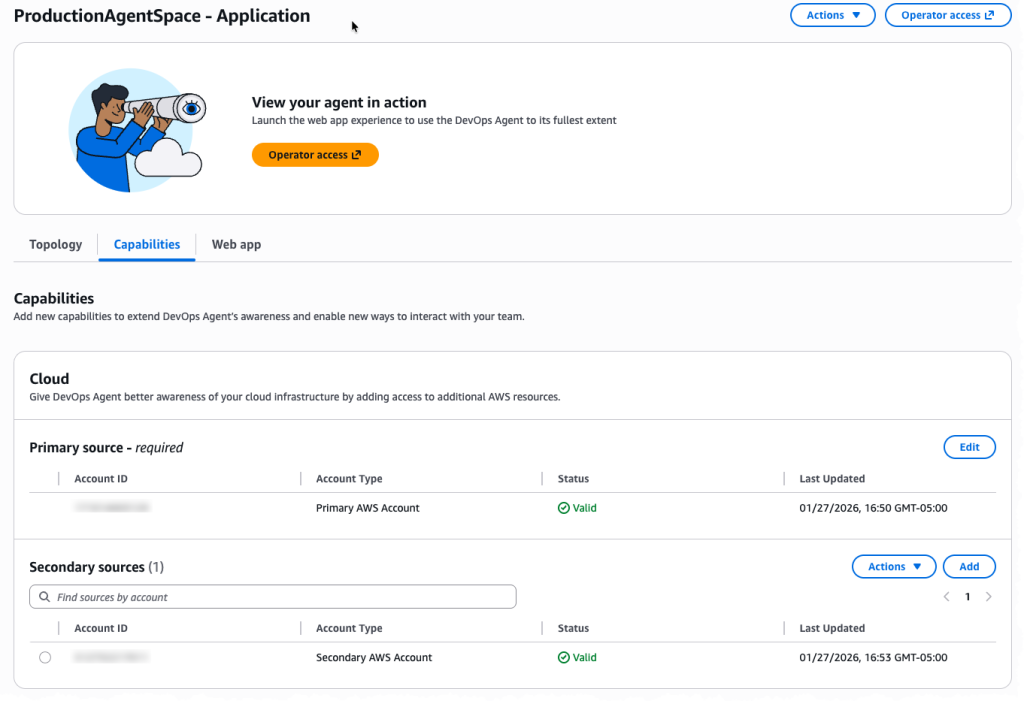
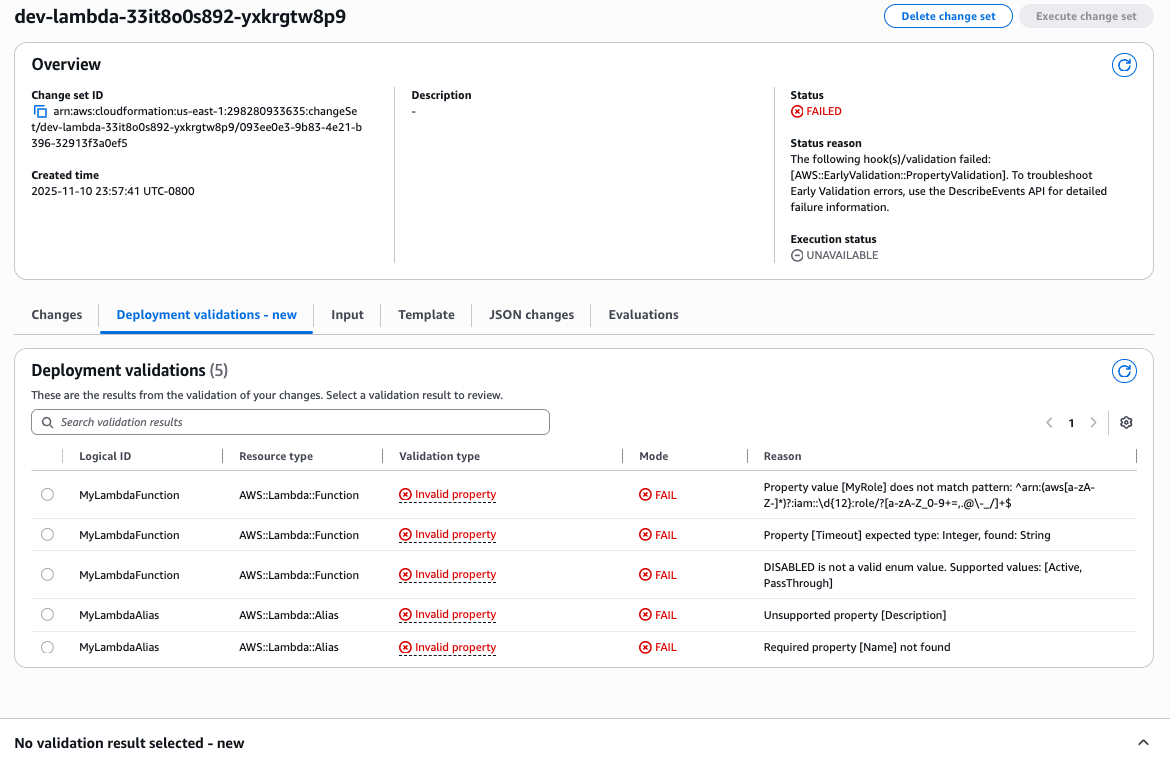
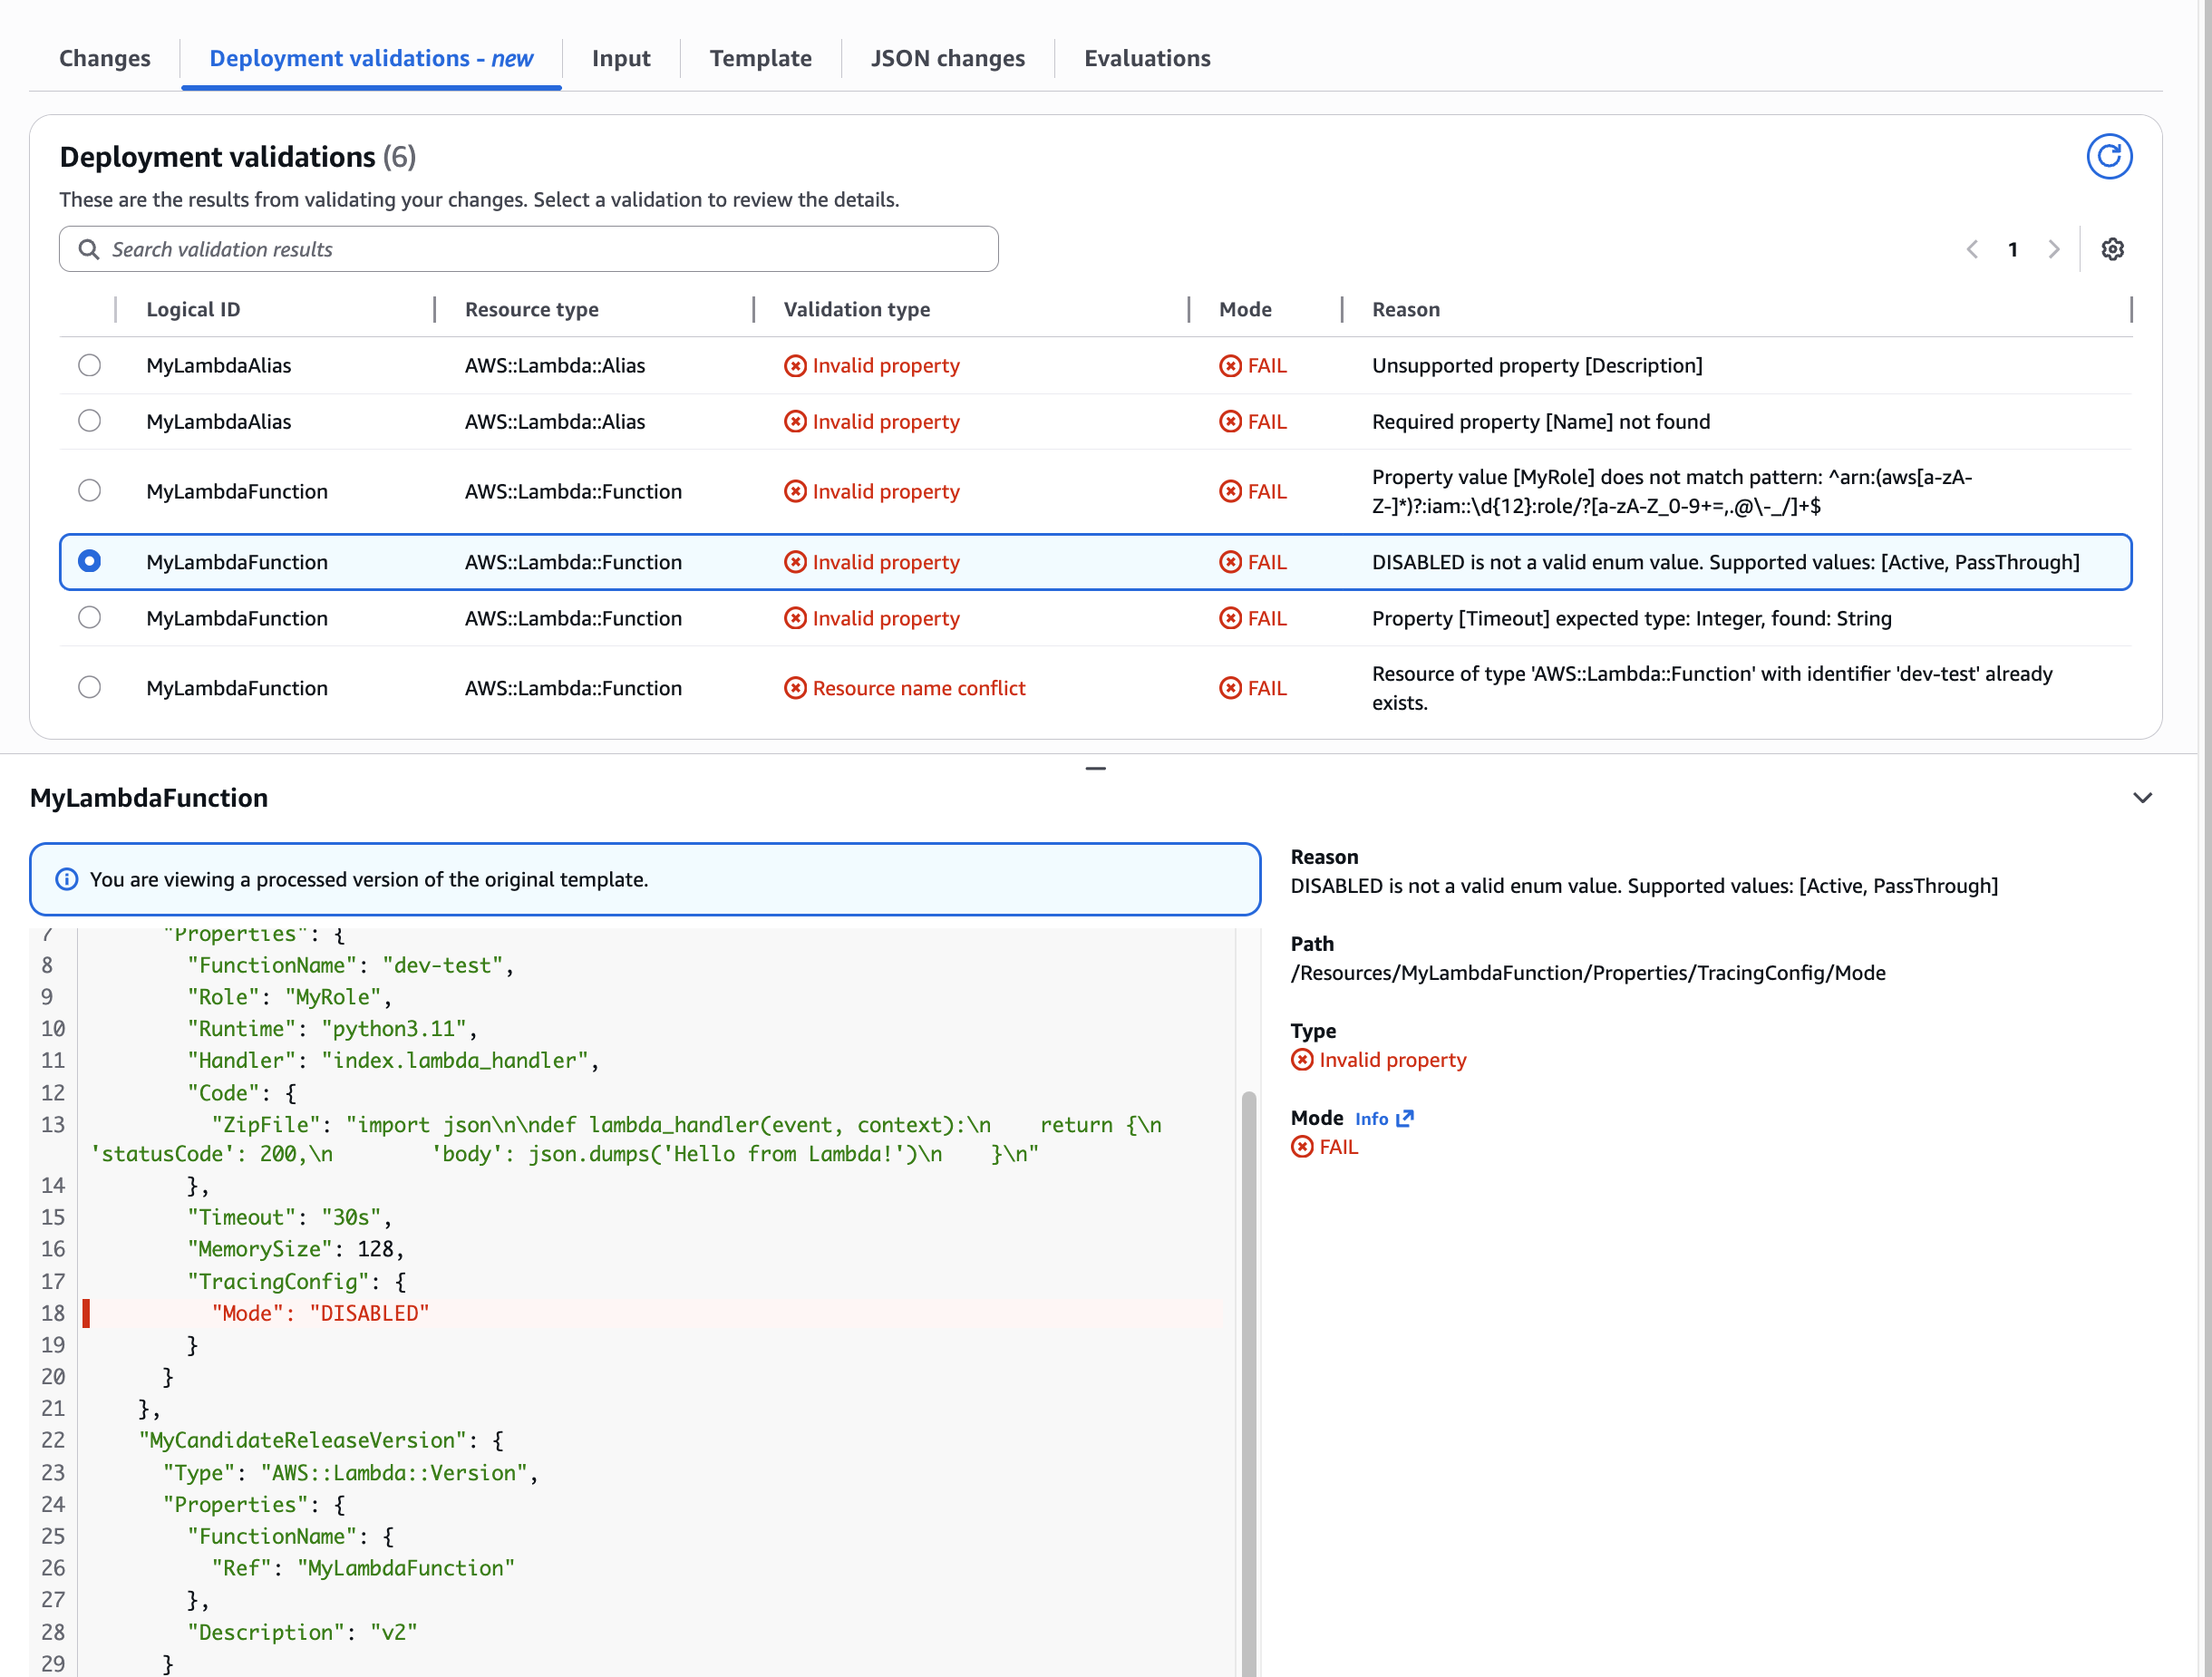
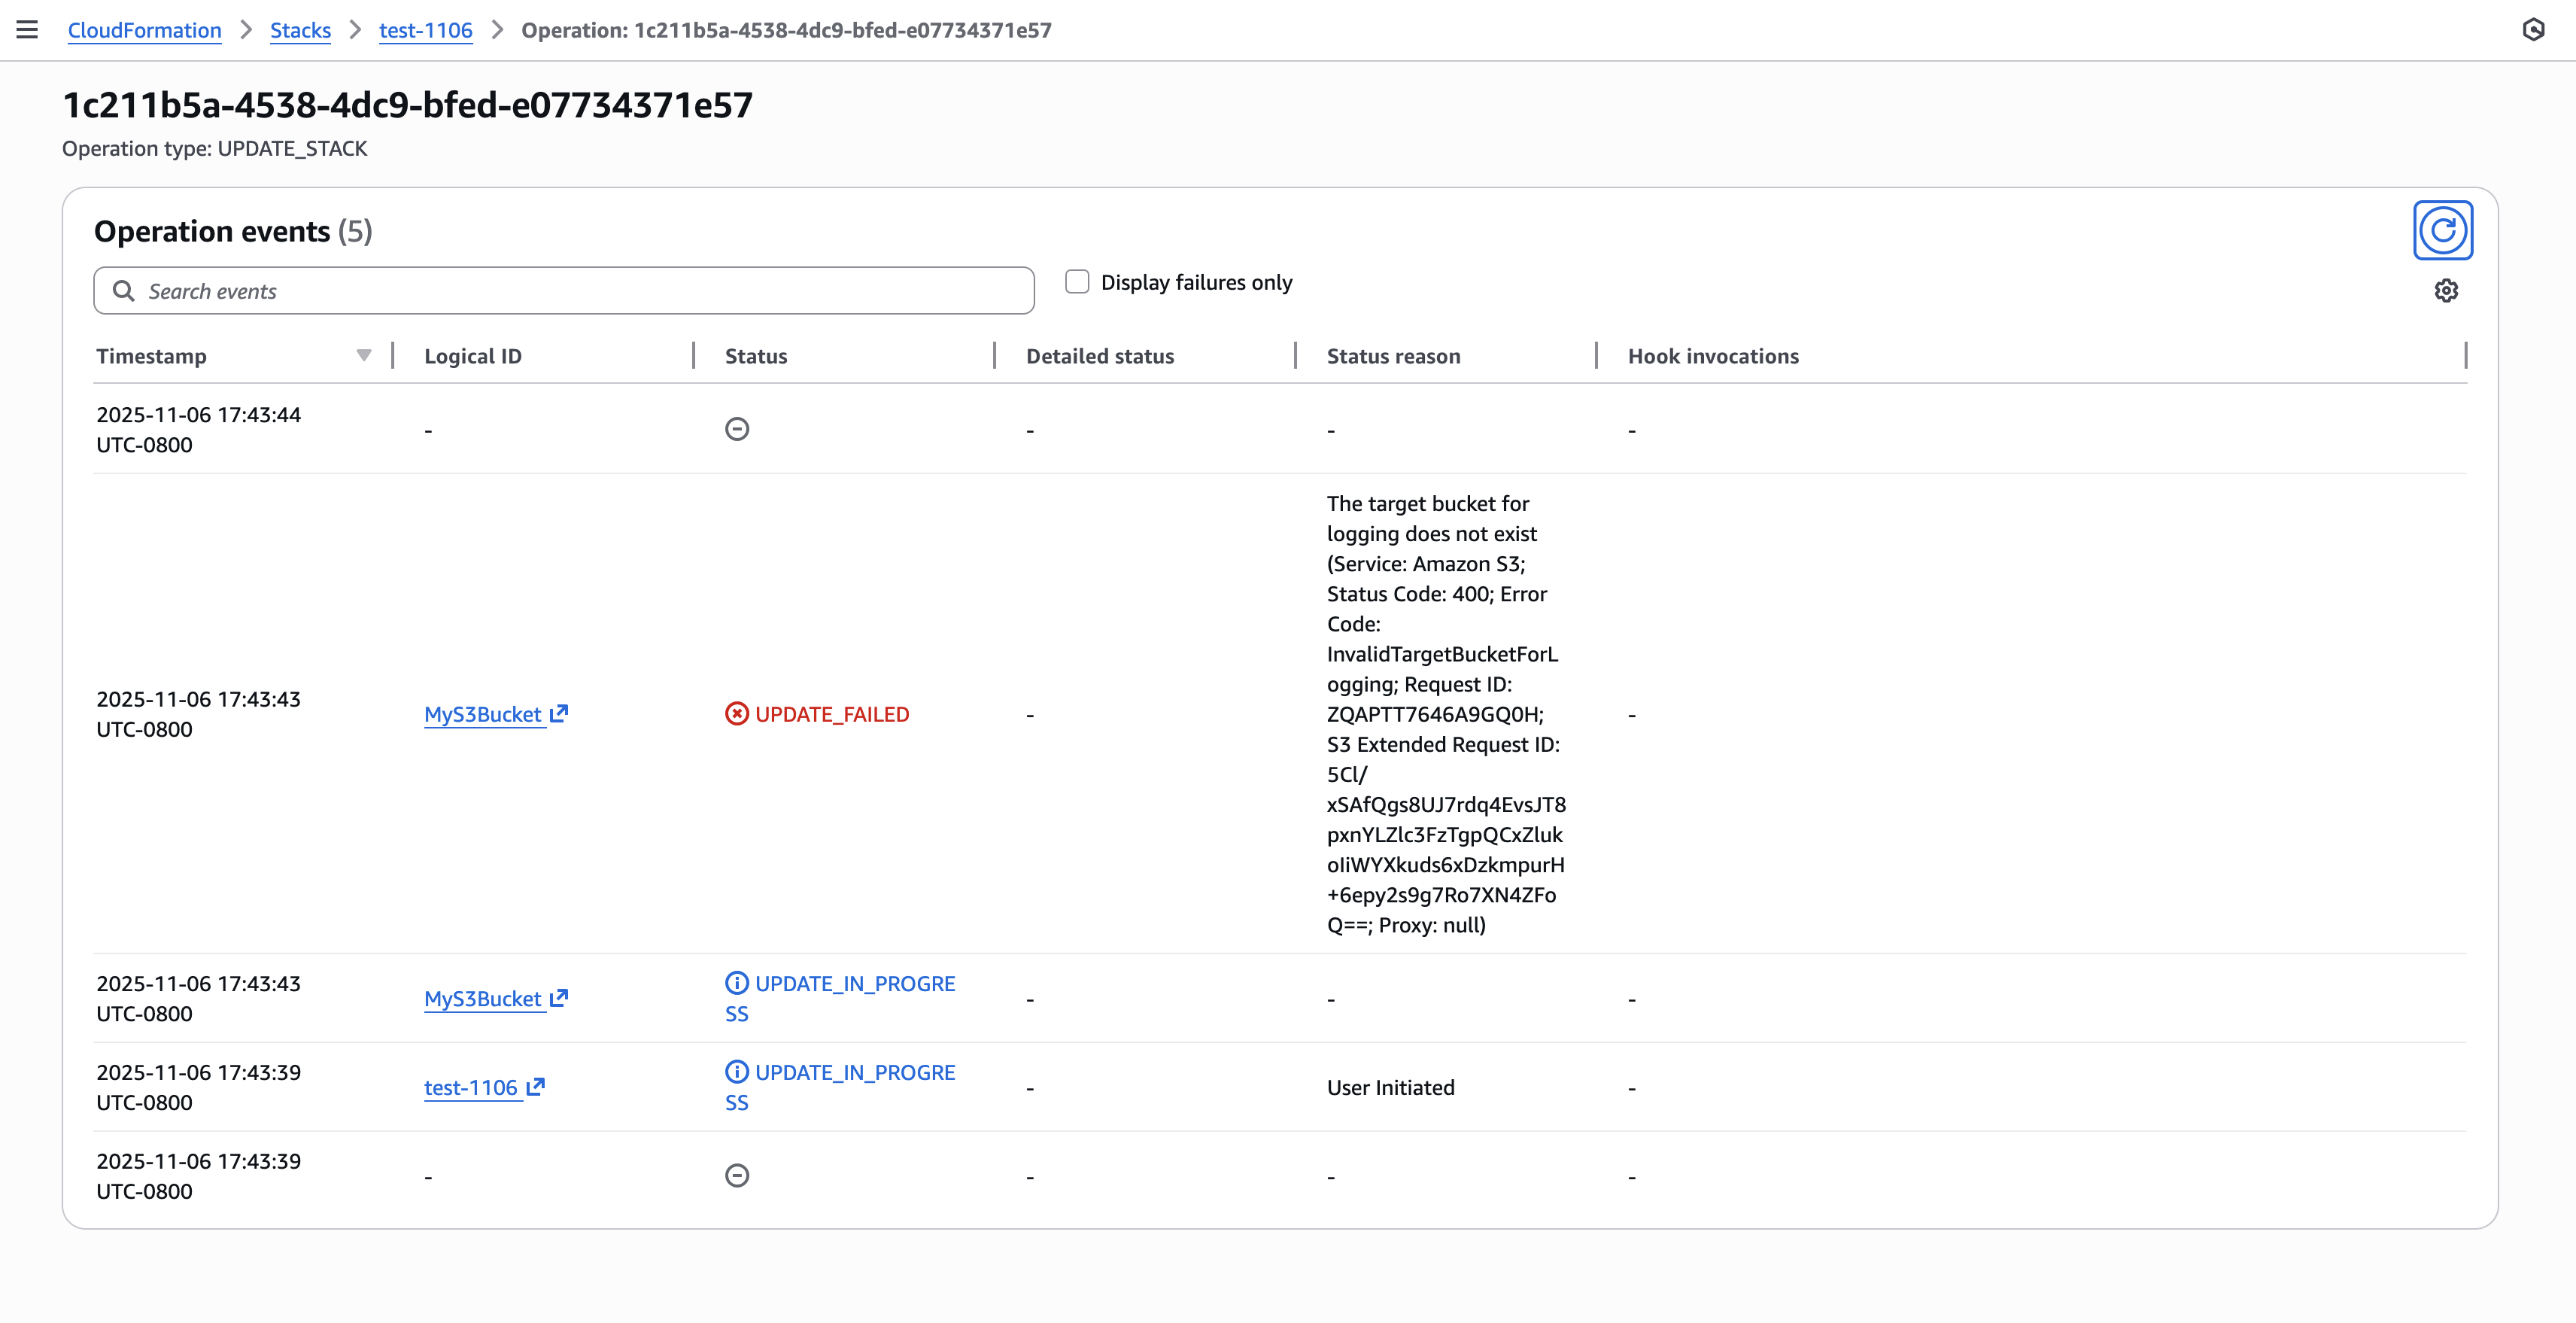 Figure 3: New CloudFormation stack operation page