This post is co-authored with Gil Irizarry, Mae Wells-Kress and Craig Harmon from Babel Street.
Can your system tell “John Smith” apart from “John Smith”?
Organizations requiring identity intelligence increasingly face challenges due to complexity of matching names and entities across vast, multilingual, and constantly evolving datasets. Whether helping border security, combating financial crimes, or maintaining regulatory compliance, the accuracy of identity and entity resolution directly determines whether threats are detected, investigations succeed, and regulatory requirements are met. Yet, linguistic diversity, transliterations, inconsistent data formats, and legacy system limitations continue to create friction, leading to false positives, missed matches, and costly manual reviews. As customers ingest and analyze petabytes of unstructured and structured data in Amazon OpenSearch Service, the need for intelligent, scalable, and multilingual matching becomes increasingly important. This is where the integration of Babel Street (an AWS Partner) with OpenSearch Service provides a solution that helps organizations enhance precision, reduce noise, and accelerate insights from their high-volume data environments.
This post explores how combining Babel Street Match with OpenSearch Service provides a solution that helps your organization to handle large-scale, multilingual data.
The growing complexity of identity and entity resolution
As organizations ingest and analyze massive volumes of multilingual and inconsistently formatted data, accurately matching names and entities becomes increasingly difficult. Variations in spelling, transliterations, semantic differences, cultural naming conventions, and incomplete or noisy records can contribute to mismatches. These challenges are compounded by legacy systems, fragmented data pipelines, operational inefficiencies, and evolving regulatory requirements—especially in sectors where precision is a requirement.
Evaluating and enhancing identity in high-volume enterprise environments
Amazon OpenSearch Service is a fully managed, scalable search and analytics service that enables organizations to ingest, search, visualize, and analyze massive volumes of data in near real time. Built to handle structured and unstructured information from diverse sources, it powers use cases ranging from security analytics and log monitoring to enterprise search and advanced analytical applications.
Babel Street delivers risk intelligence trusted by organizations across government, defense, and the private sector. The offering combines access to vast volumes of multilingual data with advanced analytics to uncover hidden identities, secure vendor networks, and identify emerging risks with precision, speed, and scale. From national security to regulatory compliance and enterprise resilience, Babel Street provides the strategic advantage needed to stay ahead of risk, safeguard operations, and protect missions.
Babel Street Match, an offering from Babel Street incorporates advanced identity risk intelligence capabilities, which enhance the precision and reliability of screening processes. This advanced solution uses sophisticated matching techniques to verify identities and identify variations in personal data—including aliases, alternate spellings, and differences in biographical details, helping organizations separate legitimate individuals from potential threats. The ability to screen names, addresses, dates, and other identifiers across different scripts and languages helps reduce false positives and negatives, helps accurately detect critical risks with transparent scoring to meet compliance and audit requirements. Further, Babel Street Match streamlines screening workflows, reduces the burden of manual reviews, and elevates the accuracy of threat detection.
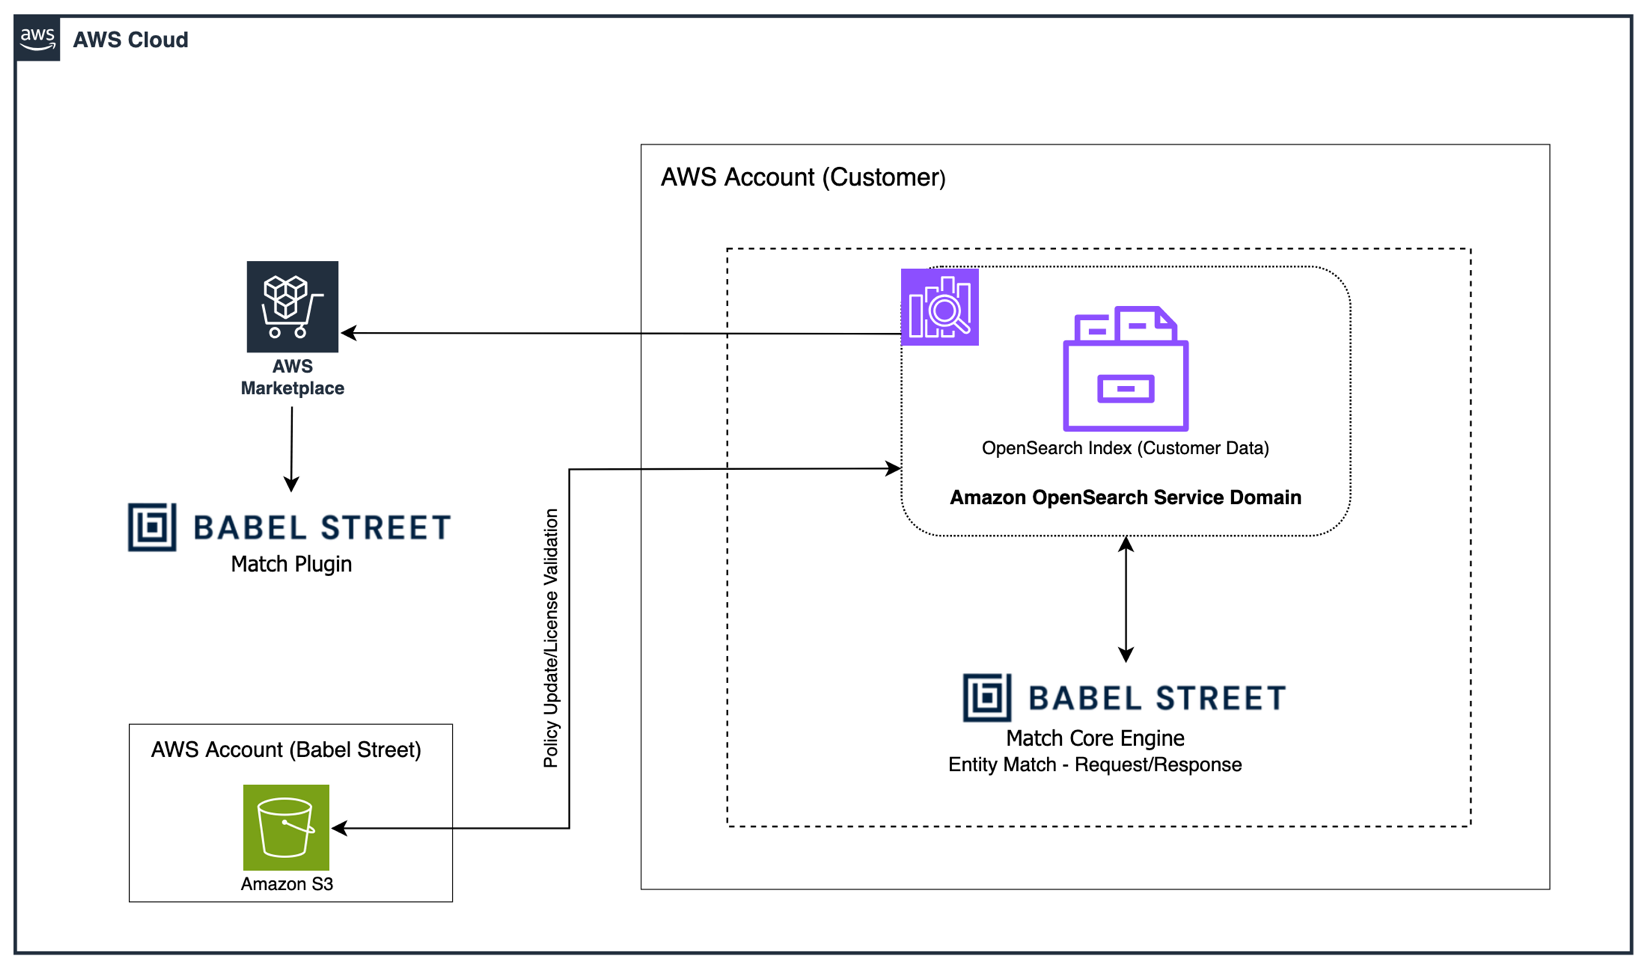
The following diagram shows the details of OpenSearch Service and Babel Street Match Plugin integration.
Babel Street Match integrates directly with the OpenSearch Service domain through a lightweight plugin that runs inside your own AWS account where you have full control of your data. The Match plugin sends encrypted match requests to Babel Street’s fully managed Match engine, where the core matching engine performs the entity-resolution logic. The results return to you in real time, enhancing your existing OpenSearch Service workflows with advanced name- and entity-matching capabilities. Meanwhile, Babel Street’s control plane handles licensing, monitoring, and AWS Marketplace integration behind the scenes, provides continuous validation, automated updates, and a seamless operational experience.
Example use cases
The solution combines enterprise-scale search and analytics with AI-powered, multilingual identity intelligence. This section showcases example use cases where integration has enhanced organizations’ capabilities.
Border Screening: Help agencies identify high-risk travelers, cargo, and networks to strengthen point-of-entry security with faster, automated risk assessment.
Financial Services Compliance: Help Financial institutions and the FinTechs that serve them by offering AI-driven solutions for name screening, adverse media monitoring, and know your customer (KYC)/know your vendor (KYV) due diligence.
Identity and Organization Screening: Help businesses needing identity and organization screening by providing AI, analytics, and advanced matching technologies to assist in addressing complex screening challenges.
Customer and Vendor Onboarding: Help governments and financial institutions by providing research, analytics, and advanced matching technologies needed to quickly and confidently onboard customers and vendors at scale.
Customer Success Stories
Here’s how leading organizations are leveraging Babel Street Match and Amazon OpenSearch Service to solve real-world identity challenges:
A European online brokerage faced AML (anti-money laundering) compliance challenges with its outdated name-matching system, which produced excessive false positives and couldn’t process longer multilingual names. After implementing Babel Street Match on OpenSearch Service, the firm achieved up to 70% better accuracy across 25 languages—significantly reducing manual work and speeding customer payments. Babel Street Match Improves FI’s Name-Matching Accuracy by Up to 70% on OpenSearch
A major border agency struggled with an outdated screening system that flagged 15% of travelers as potential watchlist matches—overwhelming agents and creating long queues. After implementing Babel Street Match, false positives dropped dramatically (from 80,000 to just 100 in one test), hardware needs fell by 70%, and travelers with common names can now pass through faster. As one stakeholder put it: “Name matching is not our biggest problem anymore.” Enabling Stronger, Safer Borders with AI-powered Screening by Babel Street Match
Getting Started with Babel Street Match for Amazon OpenSearch Service
Amazon OpenSearch Service supports third-party plugins like Babel Street Match for OpenSearch. This plugin is supported on OpenSearch version 2.15 or higher and licenses can be obtained through AWS Marketplace.
Installing Babel Street Match for Amazon OpenSearch Service
Prerequisites: Obtain the license file from Babel Street and upload it to an S3 bucket in the same AWS Region as your OpenSearch domain.
Installation Steps:
Create packages – In the OpenSearch Service console, create a package for your license file and select the Babel Street Match plugin from the available options
Associate packages – Link both the license and plugin packages to your OpenSearch domain
Verify – Monitor the domain update and confirm the plugin is active
Together, Babel Street Match and OpenSearch Service help organizations cut through false positives and catch true matches faster. The result? Greater precision, efficiency, and speed—whether protecting entities, maintaining compliance, or securing supply chains. That’s business-critical identity intelligence in action.
Explore how Babel Street Match on Amazon OpenSearch Service can elevate your organization’s identity intelligence capabilities and transform the screening operations through an interactive or customized demo on Babel Street’s website. Portions of this content describing Babel Street products and services are provided by Babel Street. AWS is not responsible for the accuracy of third-party product information.
превод от румънски Лора Ненковска, София: изд. ICU, 2025
Да пишеш без финали, защото краят вече се е случил – дискретно, неусетно до коварност, в самите гънки на ежедневието; да разказваш неумолимостта на човешката ентропия – от най-интимното до социалното. Това прави Елена Владаряну в
може би най-добрия сборник с разкази, който съм чела от много време насам.
Още по-впечатляващо е, че (макар Владаряну да е добре позната като „сърдитото момиче на румънската поезия“ още от началото на хилядолетието) сборникът „Август“ се явява неин дебют в прозата, преведен съвършено от Лора Ненковска.
В десетте разказа лично за мен прозира майсторството на американската школа (неслучайно авторката споменава Селинджър и навсякъде се усеща онова особено, тлеещо неспокойство, прикрито зад мнима ведрост и игривост („Осени ме внезапно мисълта, че ще помня този ден до края на живота си, щеше да бъде идеален ден, добавих щриха, и изведнъж се сетих за рибка-бананка…“), както и силата на внушението, с която т.нар. мръсни реалисти обговарят екзистенциалната драма на обикновения човек през абсолютната проза на делника му. С тази разлика, че тук разказите са обединени от темата за „почивката“ през лятото – тоест от идеята за бягството от рутината. Слагам тази дума в кавички, защото очакваното отпускарско пространство на покой, свобода, удоволствие и дори еуфория в тези разкази придобива характера на Doppelganger на реалността – на още по-осезаем капан, принуда, безизходност.
Неслучайно и заглавието е името на най-летния и същевременно последен за сезона месец – зноен, жежък, но вече презрял, граничен, в прехода към разпада и предстоящата смърт, която свързваме с есента. Неговата задушлива атмосфера и прашна сухота се превръщат в психологически фон на конфликтите.
На фона на очакваната отпускарска лежерност се разгръщат насилие и травми; на фона на безвремието – неотложност и неспособност да се издържа повече; на фона на свободата – ограничения или безизходност.
Драмата в тези разкази е хем инертно банална, хем неистово имплодираща, но решена в крайно минималистични жестове – случайна реплика, ретроспективно подхвърляне, неочаквано наблюдение, жест, зад които се крие същинската, неразказна пряко „история“. Дори самоубийствата тук не биват потвърдени – приключването в крайна сметка е в процеса, не в резултата; важно е всичко онова, което предшества номиналния край, а сам по себе си той няма нужда да бъде назоваван.
Стилът на Владаряну е изключително подчинен на онова съвършено наративно правило: да показва, вместо да казва. Всъщност именно това кинематографично, оголено, лишено от обяснения и явна образност разказване – подобно на регистрираща скрита камера – е майсторството на нейния почерк. В сюжетите, разстлани като плажна кърпа, случващото се е скрито в диплите на привидното нищоправене, в изреждането на поредица от уж тривиални действия, реплики, детайли. И във всеки разказ идва един момент на пределно пронизване, на събуждане, концентриращо мощта му.
Макар разказите да са по-скоро лични и интимни, в тях Владаряну прави и дискретни социални и етически коментари през поведението и речта на своите герои, без да ги оставя еднозначни. Така например в „Светлана“, изправен пред очевадната простащина, грубост и агресия на един от героите, читателят в крайна сметка се чуди: нима героинята, която така категорично и заслужено осъжда поведението му, не е всъщност далеч по-емпатично инертна и морално безучастна в сравнение с него? В „Концертът“ се оголва гноящото обществено насилие в лицето на алфа-мъжкаря герой, при това представител на силите на реда – и той, също като горния, плод на комплекси и дългогодишни класови наслоения и безнаказаност („всички онези психопати, които стрелят по хора на улицата и за които чуваш по телевизията“). И тогава няма значение кой към кого произвежда изстрела в края на разказа – важното е, че той е неизбежен, съвсем по чеховски.
Децата също са сред постоянните герои на Владаряну (макар самата тя да пише в предговора към българското издание: „Тук морето и лятото са за възрастни“). Малките и подрастващите са навсякъде, а отношението към тях е нюансирано и често разкрива недостатъчността и неадекватността на големите – чрез досадата или раздразнението от тях, чрез възприемането им като тежест или пречка за емоциите на възрастните, понякога като страничен шум, понякога като щит и прикритие, понякога като основание, което те закотвя за живота.
Във „Водното конче“ студенината към собственото дете, с което лесно си се сдобил и приемаш за даденост – здраво, весело, красиво, – контрастира с органичната грижа и пределна нежност на другите родители към тяхното „дефектно“ момченце, което е с проблеми в развитието; тогава всяко негово припълзяване се възприема като събитие и е повод за радост. Пак там моментното преживяване, сбъркано с неприятен, но донякъде подмолно желан флирт, всъщност снабдява с жизненоважно знание разсеялата се майка, която ще трябва да спаси детето си – защото онова, което те подлъгва, понякога може и да те избави. Отново в „Концертът“ полицаят е груб и безразличен към доведения си син – докато не се втурва насилствено да го защити, използвайки го като претекст, за да установи своя контрол и авторитет и да насочи тази грубост към другите.
Във всички случаи обаче в крехкостта на децата тук прозират бъдещите възрастни със своите емоционални щети и опустошения. Съзнанието за този неумолим, потискащ преход ясно се усеща:
… но някак си бях облекчена от мисълта, че е още малко момиче, дете, знаех, че времето неименуемо щеше да се вреже между нас. Знаех твърде добре колко смущаващи стават докосванията на другите в определен момент, особено тези на родителите ти, как ти се иска да си изградиш черупка, от която не можеш да излезеш и където никоя ласка не може да те смачка, затова се радвах, че Адела още няма черупка, че още известно време можем да бъдем деца.
В „Август“, насред абсолютния битовизъм, насред храната и кисненето, Владаряну ни предлага дълбоки екзистенциални кризи и битиен задух. Героите признават: „Празниците и ваканциите винаги са били сложни и трудни“ и
имам чувството, че се задушавам тук. А аз, понеже съм си перде, я попитах като съвършена глупачка: къде тук, в града или с брат ми? Не, не, тук, каза тя и сложи длан на главата си. Задушавам се тук.
Заслепени от собствените си травми обаче, често не виждаме (тези на) другите, както е в „Преди началото на сезона“, а понякога опитите ни да бъдем емпатични и да проявим човещина спихват в зародиш („Светлана“) или се оказват погрешни („Терасата“), нефелни, объркани. В плътското, чувствено, езиково (репликите често са разговорни до жаргонна вулгарност) присъствие на героите непрестанно се усеща и едно латентно, всеобхватно отсъствие. Те непрекъснато мислят и мечтаят някакво свое друго и другаде – сякаш никога не са докрай там. (Разбира се, важно е да се уточни, че разказвачите и главните героини са жени – но това би отворило цял един дълъг феминистичен прочит, за какъвто нямаме време.)
Във всички разкази от сборника идва един момент на тиха, но въздействаща поанта, на нарушаване на мнимия покой, на пропадане в безметежното море.
„Август“ е книга за онези пътеки на лятото, които отвеждат до натрупаната умора, невъзможното бягство, тихите кризи на зрелостта, родителството и невидимите пропуквания в женския свят,
обобщава преводачката в послеслова. Така че с право можем да определим тези майсторски истории като смразяващи протуберанси в самото сърце на лятото.
Никой от нас не чете единствено най-новите книги. Тогава защо само за тях се пише? „На второ четене“ е рубрика, в която отваряме списъците с книги, публикувани преди поне година, четем ги и препоръчваме любимите си от тях. За нея медията „Тоест“ е отличена с Националната награда „Христо Г. Данов“ (2025) за принос в представянето на българската книга.
Рубриката е част от партньорската програма Читателски клуб „Тоест“, благодарение на която активните дарители на „Тоест“ получават 20% отстъпка от коричната цена на всички книги на включените издателства. Изборът на заглавия обаче е единствено на авторите Стефан Иванов, Севда Семер и Антония Апостолова, които биха ви препоръчали тези книги и ако имаше как да се разходите с тях в книжарницата.
Modern media workflows don’t run on storage alone. They run on ecosystems—tightly integrated stacks of tools that ingest, process, analyze, move, review, and distribute content at scale. The companies we partner with aren’t just integrating with Backblaze; they’re building on it to solve real, specific problems that media teams face every day: archives that are impossible to search, file transfers that collapse over distance, review cycles that slow production to a crawl, compliance workflows that can’t keep up with library growth.
At NAB Show 2026, we’re bringing ten of those partners into booth N1259 to share what they’ve built. But the stories they’re telling aren’t just for Las Vegas—they’re for any media team trying to understand what a modern, cost-efficient, deeply integrated workflow actually looks like in practice.
Here’s a look at each partner, the problem they solve, and why it matters.
Imaginario AI: From Archive to Action
Presenter: Jose Puga, CEO and Co-Founder, Imaginario AI
Most video archives are passive. Content sits in storage, cataloged by someone who had time to do it years ago, effectively invisible to the people who could use it today. Imaginario AI flips that model.
Jose Puga’s session, “From Archive to Action: How AI Is Turning Your Video Library Into a Revenue Engine,” frames the shift from passive storage and cataloging to intelligent systems that actively surface, repurpose, and monetize content. The talk covers how marketing teams can accelerate campaigns, post-production teams can shortcut assembly, and compliance workflows can move from reactive to automated.
Imaginario is a multimodal video agentic platform that understands video in a human-like way—recognizing sounds, speech, and visual scenes without requiring time-based metadata. The platform is trusted by Warner Bros. Discovery, Sony Music, and Universal Pictures, and has won back-to-back IBC Best of Show honors in 2024 and 2025.
The Backblaze integration means content stays where it lives—no migration, no friction. As Jose puts it: “Backblaze provides our clients a scalable, reliable cloud layer that eliminates the friction of manual data transfers. Our native integration saves video teams dozens of hours by keeping content on Backblaze while unlocking high-speed AI analysis, retrieval, and repurposing in media and entertainment.”
Suite Studios: S3 Native File Streaming
Presenter: Jay Maxwell, Co-Founder & CPO, Suite Studios
Remote and distributed production teams have wrestled with the same problem for years: How do you collaborate on large media files when your team is spread across the globe? Suite’s answer is S3 Native File Streaming on Backblaze B2. The stack makes working with cloud object storage all-around easier, enabling teams to read and write data as standard objects without copying, syncing, or transferring.
Jay Maxwell’s session explores how global teams can instantly access and collaborate on large media files from anywhere—eliminating delays and accelerating production timelines. No syncing, no waiting, no workarounds. Just files that behave the way you need them to, wherever your team happens to be.
TwelveLabs: Unlocking Archive Value with Video AI
Presenter: Jordan Woods, Senior Solutions Architect, TwelveLabs
There’s a pattern across media organizations of all sizes: years of valuable archived content sitting effectively invisible because manual cataloging doesn’t scale. TwelveLabs makes that content searchable and monetizable.
Jordan Woods’ session, “Unlocking Archive Value with TwelveLabs Video Intelligence,” shows how pairing Backblaze’s cost-efficient storage with TwelveLabs’ video AI gives organizations a practical path to turn dormant archives into searchable, monetizable assets.
As Danny Nicolopoulos, Head of Strategic Partnerships at TwelveLabs, explains: “Media companies are sitting on years of valuable archived content that’s effectively invisible because manual cataloging doesn’t scale. Pairing Backblaze’s cost-efficient storage with TwelveLabs’ video AI gives organizations a practical path to turn those dormant archives into searchable, monetizable assets.”
Tillered: Full Speed Cloud Storage Over Any Distance
Presenters: Davey Goode, Founder & Stephen Ceci, Commercial Lead, Tillered
Physics is an undefeated opponent. Move data over long distances and throughput drops—no matter how fast your storage is or how much bandwidth you have. Tillered is built to remove that distance penalty.
The session, “Backblaze B2 Accelerate with Tillered: Full Speed Cloud Storage Over Any Distance,” demonstrates how the B2 Accelerate product brings Tillered’s acceleration technology to Backblaze B2, with transfers up to 34x faster as a result. No simulations—just live transfers with real results, showing what it looks like when enterprises can move data across any distance without adding bandwidth or changing workflows.
Davey Goode founded Tillered after repeatedly running into the same issue building large-scale connectivity infrastructure: No matter how much bandwidth was available, performance collapsed over distance. This session is the solution he built.
Telestream UP.Review: Decide Faster
Presenter: Sebastian Manemann, Senior Director of Product Management, Telestream
Capture, storage, and distribution have gotten faster. Review hasn’t kept up. Proxies, downloads, duplicated files—the approval workflow often undoes the speed gains made everywhere else in the pipeline.
Sebastian Manemann’s session, “Decide Faster: Real-Time Review, QC, and Delivery with Telestream UP.Review and Backblaze B2,” demos how Telestream UP.Review enables real-time, high-resolution playback and QC directly on media stored in Backblaze B2 without moving or duplicating files.
By keeping content in Backblaze as the central storage layer, teams can review instantly, validate quality, and move to delivery faster—all while maintaining a single source of truth across the workflow. As Sebastian frames it: “When you eliminate duplication and review directly from storage, you don’t just move faster—you operate smarter.”
Qencode + Sardius: A Multi-Vendor M&E Workflow in Practice
Presenters: Murad Mordukhay, CEO, Qencode, and Jason Shore & Ari Burt, Sardius Media
This one is different from the others—it’s not a product demo; it’s a case study. Sardius Media rebuilt their media pipeline around a race model: Multiple storage providers write in parallel, and the fastest result wins.
The session breaks down how Backblaze wins approximately 80% of those races, with Qencode orchestrating the encoding layer across the pipeline. It covers what the production data actually shows, and what Sardius would do differently if they were designing the workflow from scratch today.
Qencode uses machine learning to reduce file sizes by an average of 60% without sacrificing quality. Their CEO, Murad Mordukhay, sums up the partnership plainly: “The best partnerships are when two companies solve different halves of the same problem. Backblaze handles storage with the kind of reliability and transparency that perfectly aligns with how we think about transcoding. No surprises, no lock-in, just infrastructure that earns trust by performing every single day.”
Media workflows break down not just because of bad tools, but because of coordination failures between good ones. Files don’t sync. Teams duplicate work. Availability lags behind where content actually needs to be.
Christoph Jurkuhn’s session, “The Hidden Layer: Orchestrating Media Across the Stack with HiScale and Backblaze,” shows in a live demo how HiScale orchestrates media movement across distributed environments while Backblaze B2 provides the durable, scalable storage layer underneath. Files move, sync, and become available across teams and tools without delays, duplication, or manual intervention.
“Backblaze is built for straightforward, cost-efficient storage and HiScale builds on top of that to orchestrate and process your media. It’s a natural fit for modern media workflows.”
Iconik: Control Your Content
Presenter: Jeremy Strootman, Media Workflow Consultant, Iconik
At a certain scale, the problem isn’t creating content; it’s controlling it. Files get lost, search slows to a crawl, and archives become liabilities instead of assets.
Jeremy Strootman’s session, “Control Your Content: Turning Media Chaos into Operational Advantage,” demos how Iconik and Backblaze B2 give teams operational control over their media: making content instantly searchable, accessible, and reusable across the entire workflow.
With a foundational background in storage and archiving, Jeremy has spent over two decades helping content creators maximize efficiency and productivity across the entire media lifecycle, from ingest to archive. His perspective: “Backblaze gives us the scalable foundation; Iconik gives teams control over how that content is actually used.”
ToolsOnAir: Modern Broadcast Workflows on Backblaze
Presenter: Peter Steiner, Chief Business Officer, ToolsOnAir
Peter Steiner’s session, “Record, Store, Play: Modern Broadcast Workflows on Backblaze,” brings ToolsOnAir’s deep broadcast expertise to bear on what it looks like to build a complete ingest-to-playout workflow with Backblaze B2 as the storage foundation.
ToolsOnAir has been building Apple-based broadcast solutions for over a decade, with deployments across broadcast, ingest, and storage workflows worldwide. This session is for anyone running live or near-live operations who wants to understand what a modern, cloud-native broadcast stack actually looks like in practice.
The final session tackles a problem that’s only growing: As video libraries scale into the billions of assets, compliance workflows built for smaller operations don’t hold.
Ethan Steininger’s session, “What You Miss Can Cost You: AI-Powered Media Compliance at Scale on Mixpeek and Backblaze B2,” shows how Mixpeek’s multimodal AI infrastructure platform transforms unstructured content—video, images, audio, and documents—into searchable, programmable assets through a unified API.
Before founding Mixpeek, Ethan led search at MongoDB, and today Mixpeek powers enterprise workflows across media, adtech, healthcare, and brand safety, with core technology spanning feature extraction, multimodal retrieval, and a custom-built distributed vector store engineered for billion-scale workloads.
The Bigger Picture
Ten companies, one through-line: storage that integrates cleanly across the entire media stack changes what’s possible. As I put it in my article for Post Perspective:
What we are seeing is a broader realization that infrastructure decisions directly shape how teams build and operate. When pricing models penalize access or iteration, teams naturally limit how often they experiment or how much data they retain. That has a direct impact on product velocity and long-term value creation.
Backblaze didn’t have to react to this shift; it’s how we have always approached the market. Our cost model removes barriers like egress and transaction fees so teams can operate freely. That allows media organizations to focus on where value is actually created—whether that is content, audience engagement, or new AI-driven capabilities—while still maintaining craft excellence.
When your foundation is cost-efficient, S3-compatible, and built for reliability at scale, every tool in the ecosystem above it gets to do its best work. That’s what we mean when we talk about “building the future of media workflows”—not just that Backblaze stores your files, but that it enables the ecosystem built on top of it.
Join Us at NAB Show 2026
We’d love to show you around. Whether you want to catch one of the in-booth presentations, sit down for a workflow consultation, or talk through your specific storage and integration challenges, our team will be on-site all week.
Did you know that, at GitHub, we host all of our own source code on github.com? We do this because we’re our own biggest customer—testing out changes internally before they go to users. However, there’s one downside: If github.com were ever to go down, we wouldn’t be able to access our own source code.
This is what you’d call a very simple circular dependency: to deploy GitHub, we needed GitHub. If GitHub is down, then we wouldn’t be able to deploy something to fix it. We mitigate this by maintaining a mirror of our code for fixing forward and built assets for rolling back.
So we’re done, right? Problem solved? Nope, there are more circular dependencies to consider. For example, how do you stop a deployment script introducing a circular dependency of its own on an internal service or downloading a binary from GitHub?
When we started to design our new host-based deployment system, we evaluated some new approaches to prevent deployment code from creating circular dependencies. We found that using eBPF, we could selectively monitor and block those calls. In this blog post, we’ll take you through our findings and show how you can get started writing your own eBPF programs.
Types of circular dependencies
Let’s start by looking at the types of circular dependencies through a hypothetical scenario.
Suppose a MySQL outage occurs, which causes GitHub to be unable to serve release data from repositories. To resolve the incident, we need to roll out a configuration change to the stateful MySQL nodes that are impacted. This configuration change is applied by executing a deploy script on each node.
Now, let’s look at the different types of circular dependencies that could impact GitHub during this scenario.
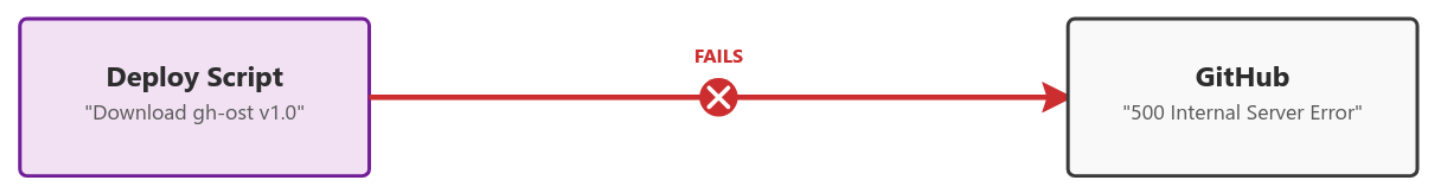
Direct dependency: The MySQL deploy script attempts to pull the latest release of an open source tool from GitHub. Since GitHub can’t serve the release data (due to the outage), the script can’t complete.
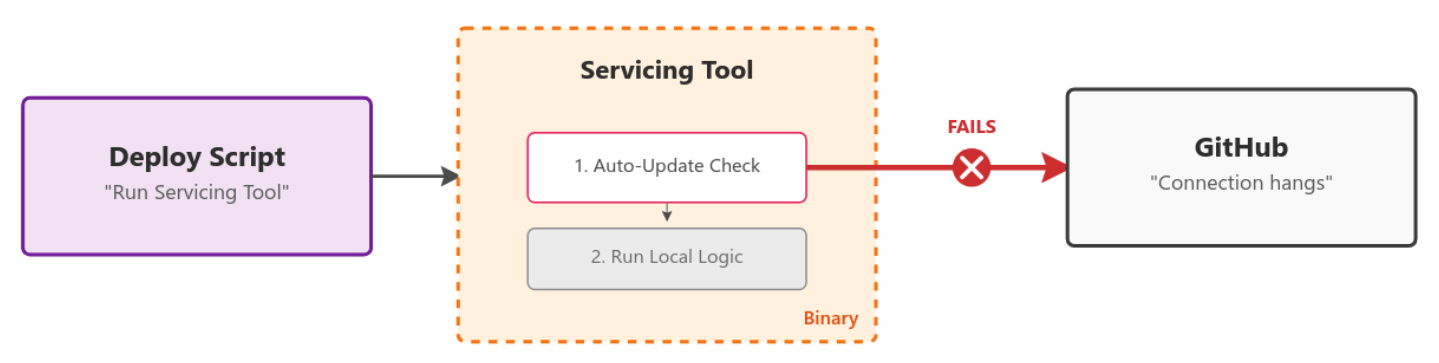
Hidden dependencies: The MySQL deploy script uses a servicing tool that is already present on the machine’s disk. However, when the tool runs, it checks GitHub to see if an update is available. If it’s unable to contact GitHub (due to the outage), the script may fail or hang, depending on how the tool handles the error when checking for updates.
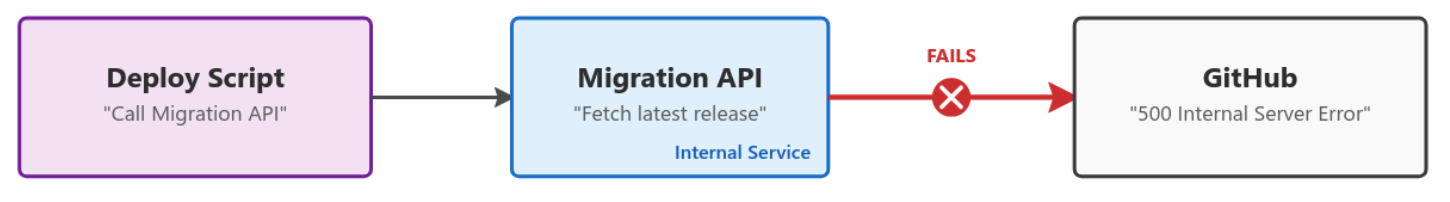
Transient dependencies: The MySQL deploy script calls, via an API, another internal service (for example, a migrations service), which in turn attempts to fetch the latest release of an open source tool from GitHub to use the new binary. The failure propagates back to the deploy script.
How do you solve these circular dependencies?
Until recently, the onus has been on every team who that owns stateful hosts to review their deployment scripts and identify circular dependencies.
In practice, however, many dependencies aren’t identified until an incident occurs, which can delay recovery.
The obvious route would be to block access to github.com from the machines to validate that the system can deploy without it. But these hosts are stateful and serve customer traffic even during rolling deploys, drains, or restarts. Blocking github.com entirely would impact their ability to handle production requests.
This is where we started to look at eBPF, which lets you load custom programs into the Linux kernel and hook into core system primitives like networking.
A cGroup is a Linux primitive (used heavily by Docker but not limited to it) that enforces resource limits and isolation for sets of processes. You can create a cGroup, configure it, and move processes into it—no Docker required.
This started to look very promising. Could we create a cGroup, place only the deployment script inside it, and then limit the outbound network access of only that script? It certainly looked possible, so we started to build a proof of concept.
Building out per-process conditional network filtering with eBPF
We started on a proof of concept in go that used the cilium/ebpf library.
ebpf-go is a pure-Go library to read, modify, and load eBPF programs and attach them to various hooks in the Linux kernel.
It massively simplifies the process of authoring, building, and running programs that use eBPF. For example, to hook the BPF_PROG_TYPE_CGROUP_SKB program type, we can do this as follows: 👇
//go:generate go tool bpf2go -tags linux bpf cgroup_skb.c -- -I../headers


func main() {

   // Load pre-compiled programs and maps into the kernel.

   objs := bpfObjects{}

   if err := loadBpfObjects(&objs, nil); err != nil {

       log.Fatalf("loading objects: %v", err)

   }

   defer objs.Close()


   // Link the count_egress_packets program to the cgroup.

   l, err := link.AttachCgroup(link.CgroupOptions{

       Path:    "/sys/fs/cgroup/system.slice",

       Attach:  ebpf.AttachCGroupInetEgress,

       Program: objs.CountEgressPackets,

   })

   if err != nil {

       log.Fatal(err)

   }

   defer l.Close()


   log.Println("Counting packets...")


   // Read loop reporting the total amount of times the kernel

   // function was entered, once per second.

   ticker := time.NewTicker(1 * time.Second)

   defer ticker.Stop()


   for range ticker.C {

       var value uint64

       if err := objs.PktCount.Lookup(uint32(0), &value); err != nil {

           log.Fatalf("reading map: %v", err)

       }

       log.Printf("number of packets: %d\n", value)

   }

}
The //go:generate line handles compiling the eBPF C code and auto-generating the bpfObjects struct, which allows us to attach and interact with the program. This means a simple go build is all you need. 🥳
There was still a missing piece though: CGROUP_SKB operates on IP addresses. Given the breadth of GitHub’s systems and rate of change, keeping an up-to-date block IP list would be very hard.
Could we use more eBPF to create a DNS-based blocked list? Yes, it turns out we could.
Here is a simplified example where we rewrite any connect4 syscall targeting DNS (Port 53) to localhost:53.
cgroupLink, err := link.AttachCgroup(link.CgroupOptions{

       Path:    cgroup.Name(),

       Attach:  ebpf.AttachCGroupInet4Connect,

       Program: obj.Connect4,

   })

   if err != nil {

       return nil, fmt.Errorf("attaching eBPF program Connect4 to cgroup: %w", err)

   }
/* This is the hexadecimal representation of 127.0.0.1 address */

const __u32 ADDRESS_LOCALHOST_NETBYTEORDER = bpf_htonl(0x7f000001);


SEC("cgroup/connect4")

int connect4(struct bpf_sock_addr *ctx) {

 __be32 original_ip = ctx->user_ip4;

 __u16 original_port = bpf_ntohs(ctx->user_port);


 if (ctx->user_port == bpf_htons(53)) {

   /* For DNS Query (*:53) rewire service to backend

    * 127.0.0.1:const_dns_proxy_port */

   ctx->user_ip4 = const_mitm_proxy_address;

   ctx->user_port = bpf_htons(const_dns_proxy_port);

 }


 return 1;

}
We used this to intercept DNS queries from the cGroup and forward them to a userspace DNS proxy we run.
Now, any DNS queries initiated by the deployment script are routed through our DNS proxy. Our proxy evaluates each requested domain against our block list and uses eBPF Maps to communicate with the CGROUP_SKB program, allowing or denying the request accordingly.
If you’d like to dig into the code, here’s an early proof of concept we put together. Our current implementation has progressed since then, but this should serve as a good intro.
Like any fun project, the deeper we got, the more we realized we could do.
For example, could we correlate blocked DNS requests back to the specific command or process that triggered them, so teams could more easily debug and fix issues? Yes, we can!
As we’re redirecting all DNS calls to our userspace DNS proxy, we can look at the transaction ID of each request, find the domain being resolved, and lookup in the eBPF Map to see which process made the request. By reading /proc/{PID}/cmdline, we can even extract the full command line that triggered the request.
Then we can output a log line with all the information:
Conditionally block domains that would cause circular dependencies from deployment scripts.
Inform the owning team which command triggered the blocked request.
Provide an audit list of all domains contacted during a deployment.
Use the cGroups to enforce CPU and memory limits on deploy scripts, preventing runaway resource usage from impacting workloads.
What’s next?
Our new circular dependency detection process is live after a six-month rollout.
Now, if a team accidentally adds a problematic dependency, or if an existing binary tool we use takes a new dependency, the tooling will detect that problem and flag it to the team.
The net result is a more stable GitHub and faster mean time to recovery during incidents (due to the removal of these circular dependencies).
Are there ways for circular dependencies to still trip things up? You bet—and we’ll look to improve the tool as we discover them.
Want to dive in?
Has this piqued your interest in what you might be able to do with eBPF?
Get started by having a look through the examples in cilium/ebpf and the great documentation on the docs.ebpf.io site.
Version
15.0 of the Forgejo
code-collaboration platform has been released. Changes include
repository-specific access tokens, a number of improvements to Forgejo
Actions, user-interface enhancements, and more. Forgejo 15.0 is
considered a long-term-support (LTS) release, and will be supported
through July 15, 2027. The previous LTS, version 11.0, will reach end
of life on July 16, 2026. See the announcement and release
notes for a full list of changes.
Today, we’re announcing Claude Opus 4.7 in Amazon Bedrock, Anthropic’s most intelligent Opus model for advancing performance across coding, long-running agents, and professional work.
Claude Opus 4.7 is powered by Amazon Bedrock’s next generation inference engine, delivering enterprise-grade infrastructure for production workloads. Bedrock’s new inference engine has brand-new scheduling and scaling logic which dynamically allocates capacity to requests, improving availability particularly for steady-state workloads while making room for rapidly scaling services. It provides zero operator access—meaning customer prompts and responses are never visible to Anthropic or AWS operators—keeping sensitive data private.
According to Anthropic, Claude Opus 4.7 model provides improvements across the workflows that teams run in production such as agentic coding, knowledge work, visual understanding,long-running tasks. Opus 4.7 works better through ambiguity, is more thorough in its problem solving, and follows instructions more precisely.
Agentic coding: The model extends Opus 4.6’s lead in agentic coding, with stronger performance on long-horizon autonomy, systems engineering, and complex code reasoning tasks. According to Anthropic, the model records high-performance scores with 64.3% on SWE-bench Pro, 87.6% on SWE-bench Verified, and 69.4% on Terminal-Bench 2.0.
Knowledge work: The model advances professional knowledge work, with stronger performance on document creation, financial analysis, and multi-step research workflows. The model reasons through underspecified requests, making sensible assumptions and stating them clearly, and self-verifies its output to improve quality on the first step. According to Anthropic, the model reaches 64.4% on Finance Agent v1.1.
Long-running tasks: The model stays on track over longer horizons, with stronger performance over its full 1M token context window as it reasons through ambiguity and self-verifies its output.
Vision: the model adds high-resolution image support, improving accuracy on charts, dense documents, and screen UIs where fine detail matters.
The model is an upgrade from Opus 4.6 but may require prompting changes and harness tweaks to get the most out of the model. To learn more, visit Anthropic’s prompting guide.
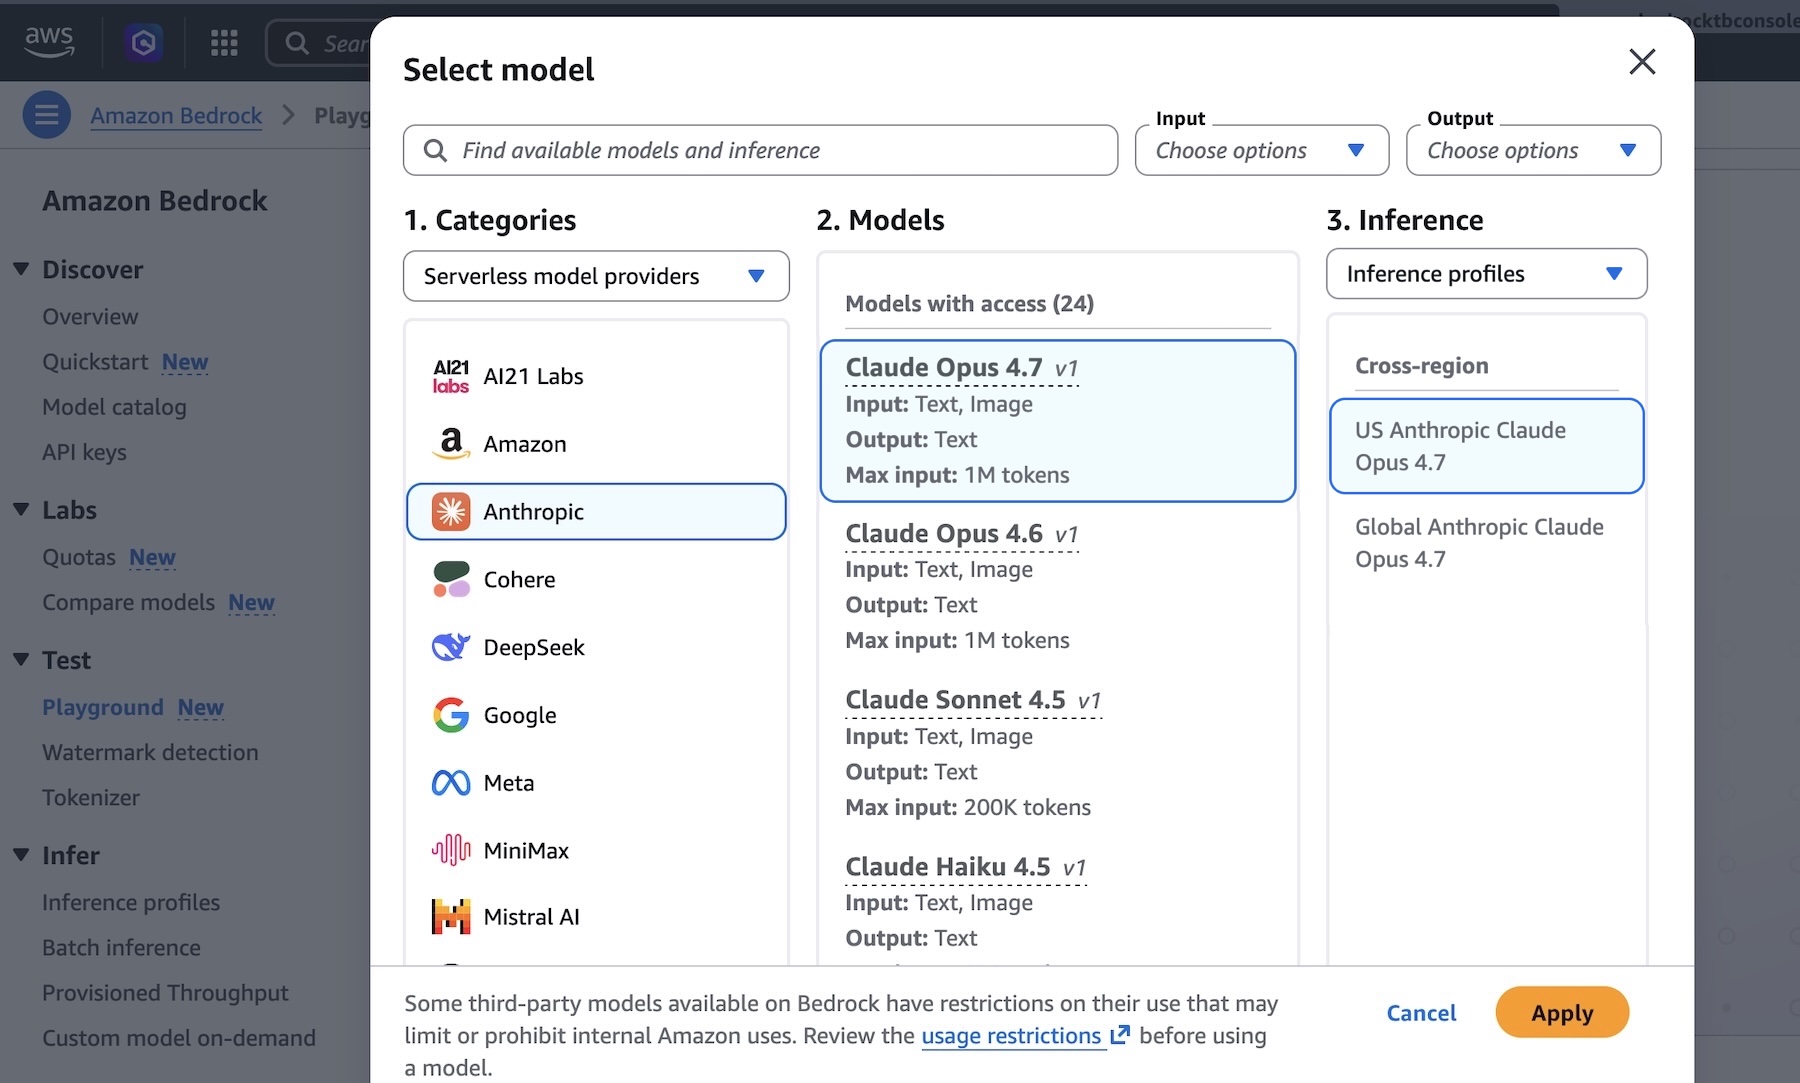
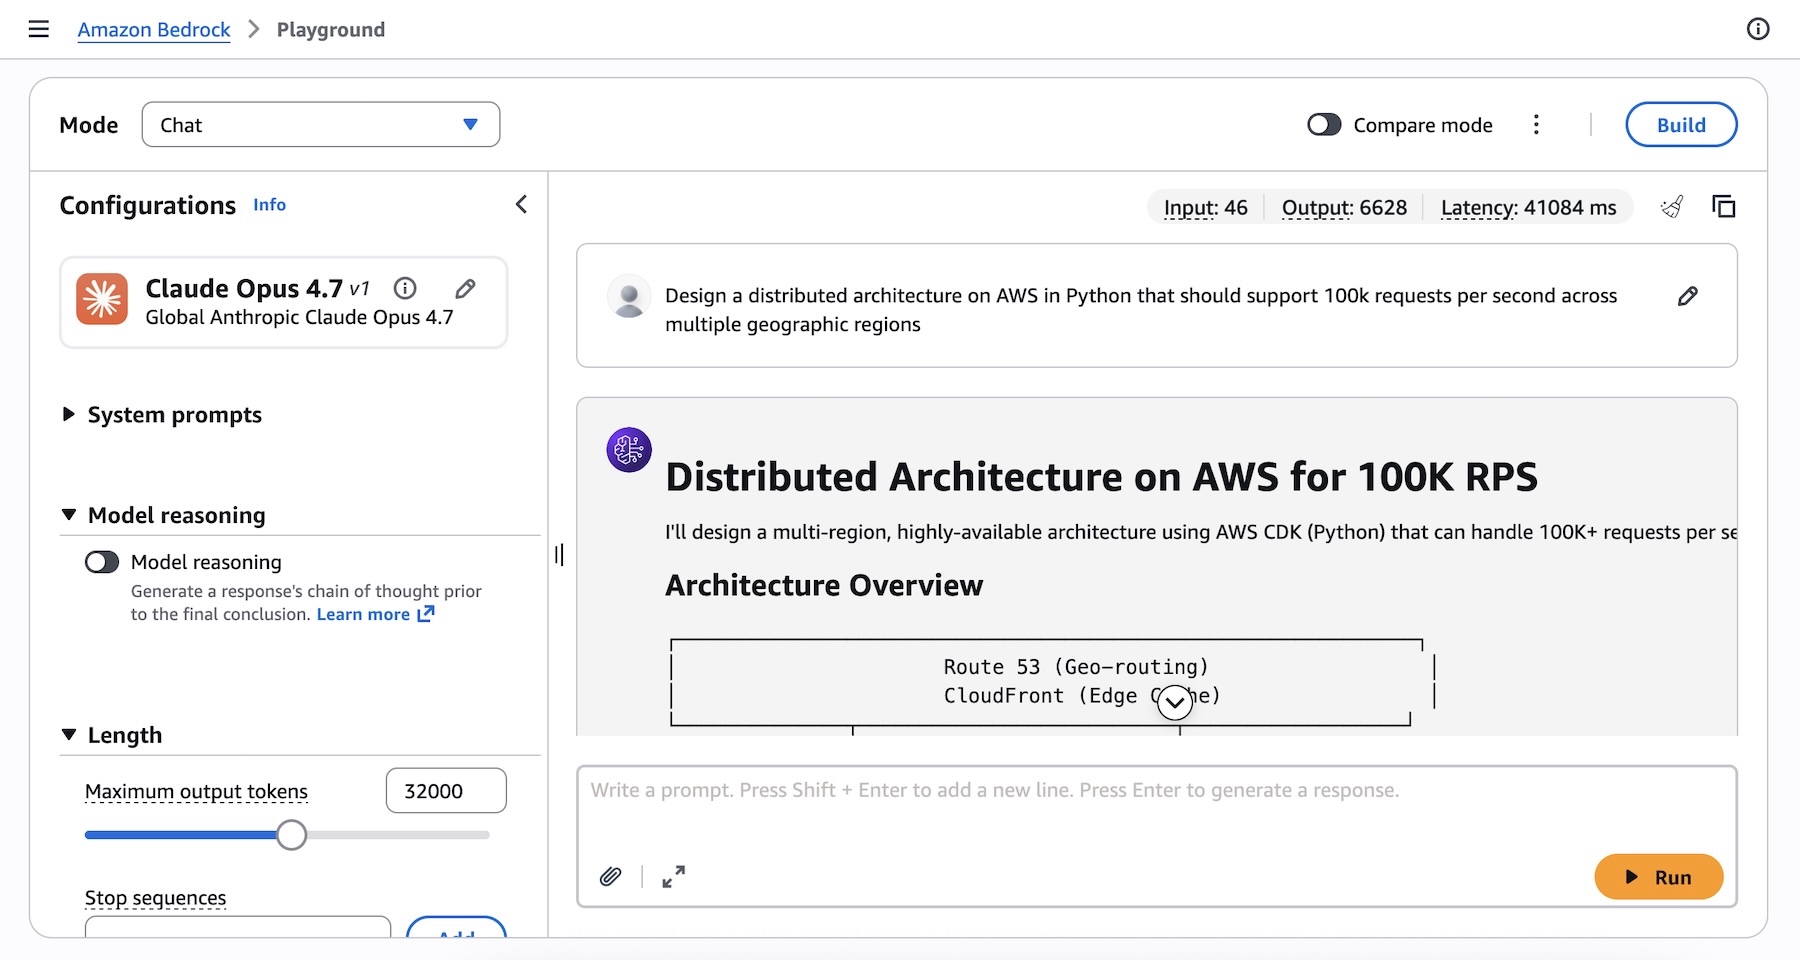
Claude Opus 4.7 model in action You can get started with Claude Opus 4.7 model in Amazon Bedrock console. Choose Playground under Test menu and choose Claude Opus 4.7 when you select model. Now, you can test your complex coding prompt with the model.
I run the following prompt example about technical architecture decision: Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions.
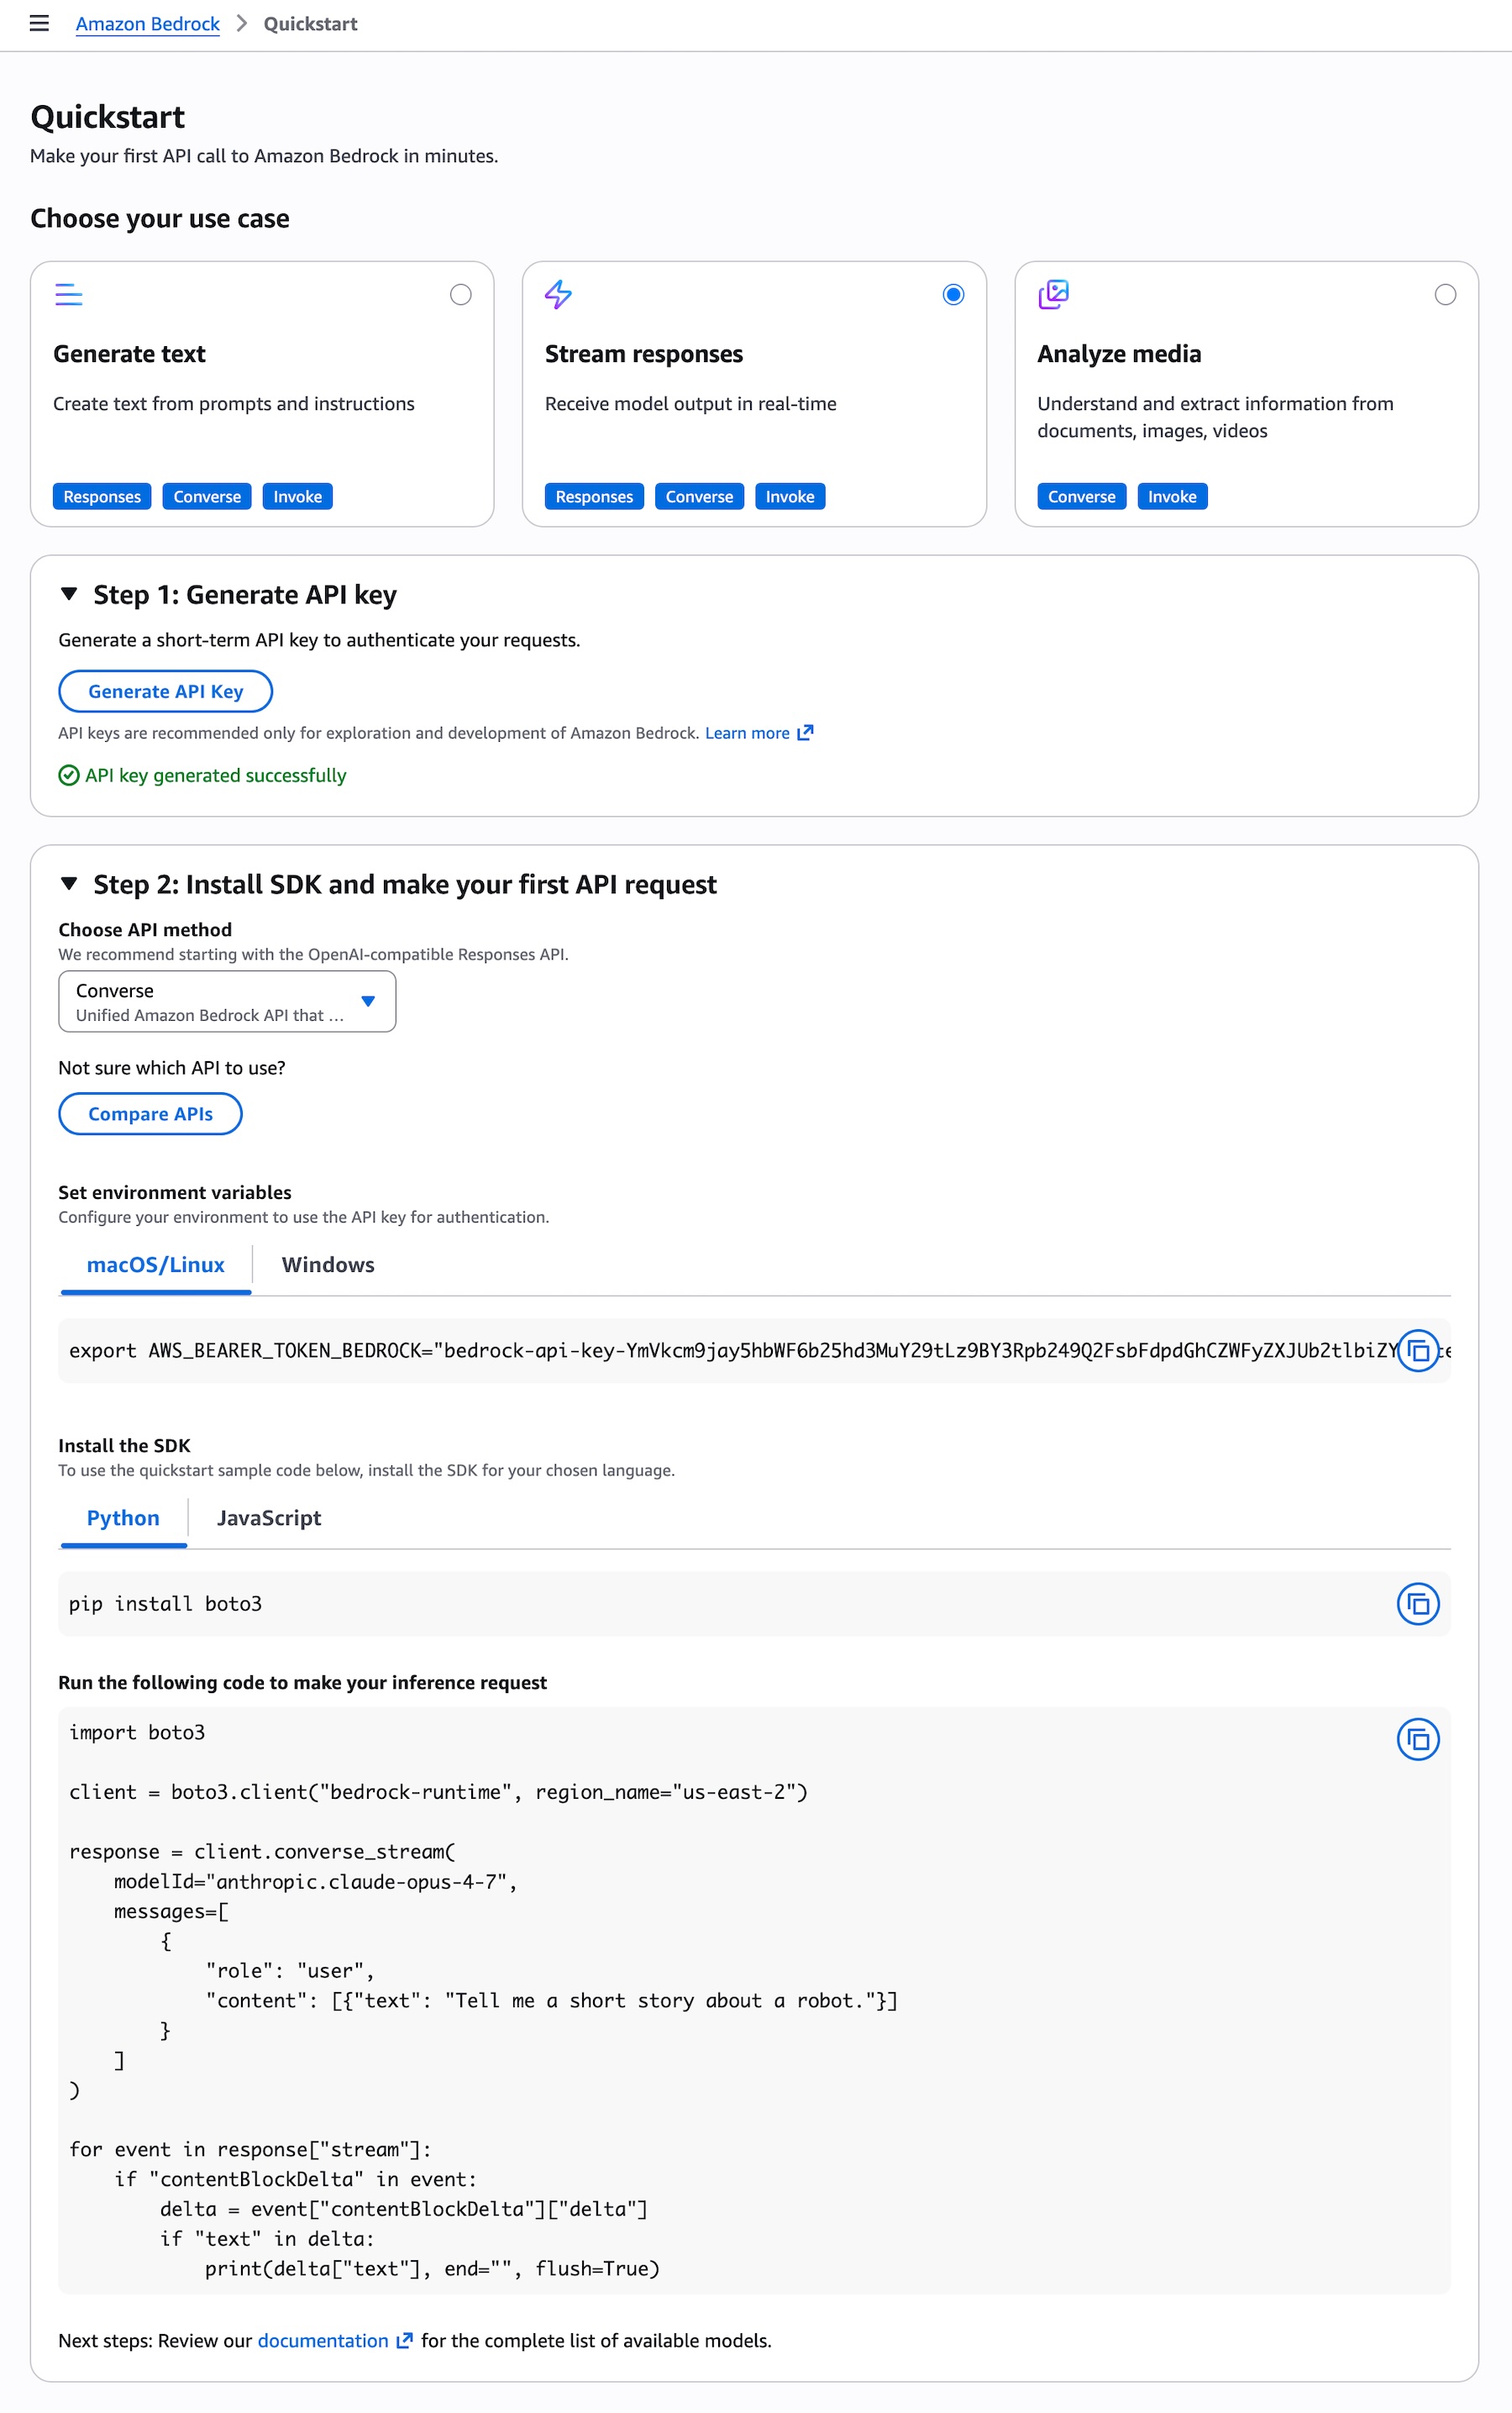
To get started with making your first API call to Amazon Bedrock in minutes, choose Quickstart in the left navigation pane in the console. After choosing your use case, you can generate a short term API key to authenticate your requests as testing purpose.
When you choose the API method such as the OpenAI-compatible Responses API, you can get sample codes to run your prompt to make your inference request using the model.
To invoke the model through the Anthropic Claude Messages API, you can proceed as follows using anthropic[bedrock] SDK package for a streamlined experience:
from anthropic import AnthropicBedrockMantle
# Initialize the Bedrock Mantle client (uses SigV4 auth automatically)
mantle_client = AnthropicBedrockMantle(aws_region=REGION)
# Create a message using the Messages API
message = mantle_client.messages.create(
    model="anthropic.claude-opus-4-7",
    max_tokens=2048,
    messages=[
	    {"role": "user", "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions"}
    ]
)
print(message.content[0].text)
You can also run the following command to invoke the model directly to bedrock-runtime endpoint using the AWS CLI and the Invoke API:
aws bedrock-runtime invoke-model \
 --model-id anthropic.claude-opus-4-7 \
 --region us-east-1 \
 --body '{"messages": [{"role": "user", "content": "Design a distributed architecture on AWS in Python that should support 100k requests per second across multiple geographic regions."}], "max_tokens": 512, "temperature": 0.5, "top_p": 0.9}' \
 --cli-binary-format raw-in-base64-out \
invoke-model-output.txt
For more intelligent reasoning capability, you can use Adaptive thinking with Claude Opus 4.7, which lets Claude dynamically allocate thinking token budgets based on the complexity of each request.
Things to know Let me share some important technical details that I think you’ll find useful.
Choosing APIs: You can choose from a variety of Bedrock APIs for model inference, as well as the Anthropic Messages API. The Bedrock-native Converse API supports multi-turn conversations and Guardrails integration. The Invoke API provides direct model invocation and lowest-level control.
Scaling and capacity: Bedrock’s new inference engine is designed to rapidly provision and serve capacity across many different models. When accepting requests, we prioritize keeping steady state workloads running, and ramp usage and capacity rapidly in response to changes in demand. During periods of high demand, requests are queued, rather than rejected. Up to 10,000 requests per minute (RPM) per account per Region are available immediately, with more available upon request.
Now available Anthropic’s Claude Opus 4.7 model is available today in the US East (N. Virginia), Asia Pacific (Tokyo), Europe (Ireland), and Europe (Stockholm) Regions; check the full list of Regions for future updates. To learn more, visit the Claude by Anthropic in Amazon Bedrock page and the Amazon Bedrock pricing page.
An agent needs to be powered by a large language model. A few weeks ago, we announced that Workers AI is officially entering the arena for hosting large open-source models like Moonshot’s Kimi K2.5. Since then, we’ve made Kimi K2.5 3x faster and have more model additions in-flight. These models have been the backbone of a lot of the agentic products, harnesses, and tools that we have been launching this week.
Hosting AI models is an interesting challenge: it requires a delicate balance between software and very, very expensive hardware. At Cloudflare, we’re good at squeezing every bit of efficiency out of our hardware through clever software engineering. This is a deep dive on how we’re laying the foundation to run extra-large language models.
Hardware configurations
As we mentioned in our previous Kimi K2.5 blog post, we’re using a variety of hardware configurations in order to best serve models. A lot of hardware configurations depend on the size of inputs and outputs that users are sending to the model. For example, if you are using a model to write fanfiction, you might give it a few small prompts (input tokens) while asking it to generate pages of content (output tokens).
Conversely, if you are running a summarization task, you might be sending in hundreds of thousands of input tokens, but only generating a small summary with a few thousand output tokens. Presented with these opposing use cases, you have to make a choice — should you tune your model configuration so it’s faster at processing input tokens, or faster at generating output tokens?
When we launched large language models on Workers AI, we knew that most of the use cases would be used for agents. With agents, you send in a large number of input tokens. It starts off with a large system prompt, all the tools, MCPs. With the first user prompt, that context keeps growing. Each new prompt from the user sends a request to the model, which consists of everything that was said before — all the previous user prompts, assistant messages, code generated, etc. For Workers AI, that means we had to focus on two things: fast input token processing and fast tool calling.
Prefill decode (PD) disaggregation
One hardware configuration that we use to improve performance and efficiency is disaggregated prefill. There are two stages to processing an LLM request: prefill, which processes the input tokens and populates the KV cache, and decode, which generates output tokens. Prefill is usually compute bound, while decode is memory bound. This means that the parts of the GPU that are used in each stage are different, and since prefill is always done before decode, the stages block one another. Ultimately, it means that we are not efficiently utilizing all of our GPU power if we do both prefill and decode on a single machine.
With prefill decode disaggregation, separate inference servers are run for each stage. First, a request is sent to the prefill stage which performs prefill and stores it in its KV cache. Then the same request is sent to the decode server, with information about how to transfer the KV cache from the prefill server and begin decoding. This has a number of advantages, because it allows the servers to be tuned independently for the role they are performing, scaled to account for more input-heavy or output-heavy traffic, or even to run on heterogeneous hardware.
This architecture requires a relatively complex load balancer to achieve. Beyond just routing the requests as described above, it must rewrite the responses (including streaming SSE) of the decode server to include information from the prefill server such as cached tokens. To complicate matters, different inference servers require different information to initiate the KV cache transfer. We extended this to implement token-aware load balancing, in which there is a pool of prefill and decode endpoints, and the load balancer estimates how many prefill or decode tokens are in-flight to each endpoint in the pool and attempts to spread this load evenly.
After our public model launch, our input/output patterns changed drastically again. We took the time to analyze our new usage patterns and then tuned our configuration to fit our customer’s use cases.
Here’s a graph of our p90 Time to First Token drop after shifting traffic to our new PD disaggregated architecture, whilst request volume increased, using the same quantity of GPUs. We see a significant improvement in the tail latency variance.
Similarly, p90 time per token went from ~100 ms with high variance to 20-30 ms, a 3x improvement in intertoken latency.
Prompt Caching
Since agentic use cases usually have long contexts, we optimize for efficient prompt caching in order to not recompute input tensors on every turn. We leverage a header called x-session-affinity in order to help requests route to the right region that previously had the computed input tensors. We wrote about this in our original blog post about launching large LLMs on Workers AI. We added session affinity headers to popular agent harnesses like OpenCode, where we noticed a significant increase in total throughput. A small difference in prompt caching from our users can sum to a factor of additional GPUs needed to run a model. While we have KV-aware routing internally, we also rely on clients sending the x-session-affinity in order to be explicit about prompt caching. We incentivize the use of the header by offering discounted cached tokens. We highly encourage users to leverage prompt caching in order to have faster inference and cheaper pricing.
We worked with our heaviest internal users to adopt this header. The result was an increase in input token cache hit ratios from 60% to 80% during peak times. This significantly increases the request throughput that we can handle, while offering better performance for interactive or time-sensitive sessions like OpenCode or AI code reviews.
KV-cache optimization
As we’re serving larger models now, one instance can span multiple GPUs. This means that we had to find an efficient way to share KV cache across GPUs. KV cache is where all the input tensors from prefill (result of prompts in a session) are stored, and initially lives in the VRAM of a GPU. Every GPU has a fixed VRAM size, but if your model instance requires multiple GPUs, there needs to be a way for the KV cache to live across GPUs and talk to each other. To achieve this for Kimi, we leveraged Moonshot AI’s Mooncake Transfer Engine and Mooncake Store.
Mooncake’s Transfer Engine is a high-performance data transfer framework. It works with different Remote Direct Memory Access (RDMA) protocols such as NVLink and NVMe over Fabric, which enables direct memory-to-memory data transfer without involving the CPU. It improves the speed of transferring data across multiple GPU machines, which is particularly important in multi-GPU and multi-node configurations for models.
When paired with LMCache or SGLang HiCache, the cache is shared across all nodes in the cluster, allowing a prefill node to identify and re-use a cache from a previous request that was originally pre-filled on a different node. This eliminates the need for session aware routing within a cluster and allows us to load balance the traffic much more evenly. Mooncake Store also allows us to extend the cache beyond GPU VRAM, and leverage NVMe storage. This extends the time that sessions remain in cache, improving our cache hit ratio and allowing us to handle more traffic and offer better performance to users.
Speculative decoding
LLMs work by predicting the next token in a sequence, based on the tokens that came before it. With a naive implementation, models only predict the next n token, but we can actually make it predict the next n+1, n+2… tokens in a single forward pass of the model. This popular technique is known as speculative decoding, which we’ve written about in a previous post on Workers AI.
With speculative decoding, we leverage a smaller LLM (the draft model) to generate a few candidate tokens for the target model to choose from. The target model then just has to select from a small pool of candidate tokens in a single forward pass. Validating the tokens is faster and less computationally expensive than using the larger target model to generate the tokens. However, quality is still upheld as the target model ultimately has to accept or reject the draft tokens.
In agentic use cases, speculative decoding really shines because of the volume of tool calls and structured outputs that models need to generate. A tool call is largely predictable — you know there will be a name, description, and it’s wrapped in a JSON envelope.
To do this with Kimi K2.5, we leverage NVIDIA’s EAGLE-3 (Extrapolation Algorithm for Greater Language-model Efficiency) draft model. The levers for tuning speculative decoding include the number of future tokens to generate. As a result, we’re able to achieve high-quality inference while speeding up tokens per second throughput.
Infire: our proprietary inference engine
As we announced during Birthday Week in 2025, Cloudflare has a proprietary inference engine, Infire, that makes machine learning models faster. Infire is an inference engine written in Rust, designed to support Cloudflare’s unique challenges with inference given our distributed global network. We’ve extended Infire support for this new class of large language models we are planning to run, which meant we had to build a few new features to make it all work.
Multi-GPU support
Large language models like Kimi K2.5 are over 1 trillion parameters, which is about 560GB of model weights. A typical H100 has about 80GB of VRAM and the model weights need to be loaded in GPU memory in order to run. This means that a model like Kimi K2.5 needs at least 8 H100s in order to load the model into memory and run — and that’s not even including the extra VRAM you would need for KV Cache, which includes your context window.
Since we initially launched Infire, we had to add support for multi-GPU, letting the inference engine run across multiple GPUs in either pipeline-parallel or tensor-parallel modes with expert-parallelism supported as well.
For pipeline parallelism, Infire attempts to properly load balance all stages of the pipeline, in order to prevent the GPUs of one stage from starving while other stages are executing. On the other hand, for tensor parallelism, Infire optimizes for reducing cross-GPU communication, making it as fast as possible. For most models, utilizing both pipeline parallelism and tensor parallelism in tandem provides the best balance of throughput and latency.
Even lower memory overhead
While already having much lower GPU memory overhead than vLLM, we optimized Infire even further, tightening the memory required for internal state like activations. Currently Infire is capable of running Llama 4 Scout on just two H200 GPUs with more than 56 GiB remaining for KV-cache, sufficient for more than 1.2m tokens. Infire is also capable of running Kimi K2.5 on 8 H100 GPUs (yes that is H100), with more than 30 GiB still available for KV-cache. In both cases you would have trouble even booting vLLM in the first place.
Faster cold-starts
While adding multi-GPU support, we identified additional opportunities to improve boot times. Even for the largest models, such as Kimi K2.5, Infire can begin serving requests in under 20 seconds. The load times are only bounded by the drive speed.
Maximizing our hardware for faster throughput
Investing in our proprietary inference engine enables us to maximize our hardware by getting up to 20% higher tokens per second throughput on unconstrained systems, and also enabling us to use lower-end hardware to run the latest models, where it was previously completely infeasible.
The journey doesn’t end
New technologies, research, and models come out on a weekly basis for the machine learning community. We’re continuously optimizing our technology stack in order to provide high-quality, performant inference for our customers while operating our GPUs efficiently. If these sound like interesting challenges for you – we’re hiring!
AI models are changing quickly: the best model to use for agentic coding today might in three months be a completely different model from a different provider. On top of this, real-world use cases often require calling more than one model. Your customer support agent might use a fast, cheap model to classify a user’s message; a large, reasoning model to plan its actions; and a lightweight model to execute individual tasks.
This means you need access to all the models, without tying yourself financially and operationally to a single provider. You also need the right systems in place to monitor costs across providers, ensure reliability when one of them has an outage, and manage latency no matter where your users are.
These challenges are present whenever you’re building with AI, but they get even more pressing when you’re building agents. A simple chatbot might make one inference call per user prompt. An agent might chain ten calls together to complete a single task and suddenly, a single slow provider doesn’t add 50ms, it adds 500ms. One failed request isn’t a retry, but suddenly a cascade of downstream failures.
Since launching AI Gateway and Workers AI, we’ve seen incredible adoption from developers building AI-powered applications on Cloudflare and we’ve been shipping fast to keep up! In just the past few months, we’ve refreshed the dashboard, added zero-setup default gateways, automatic retries on upstream failures, and more granular logging controls. Today, we’re making Cloudflare into a unified inference layer: one API to access any AI model from any provider, built to be fast and reliable.
One catalog, one unified endpoint
Starting today, you can call third-party models using the same AI.run() binding you already use for Workers AI. If you’re using Workers, switching from a Cloudflare-hosted model to one from OpenAI, Anthropic, or any other provider is a one-line change.
For those who don’t use Workers, we’ll be releasing REST API support in the coming weeks, so you can access the full model catalog from any environment.
We’re also excited to share that you’ll now have access to 70+ models across 12+ providers — all through one API, one line of code to switch between them, and one set of credits to pay for them. And we’re quickly expanding this as we go.
You can browse through our model catalog to find the best model for your use case, from open-source models hosted on Cloudflare Workers AI to proprietary models from the major model providers. We’re excited to be expanding access to models from Alibaba Cloud, AssemblyAI, Bytedance, Google, InWorld, MiniMax, OpenAI, Pixverse, Recraft, Runway, and Vidu — who will provide their models through AI Gateway. Notably, we’re expanding our model offerings to include image, video, and speech models so that you can build multimodal applications
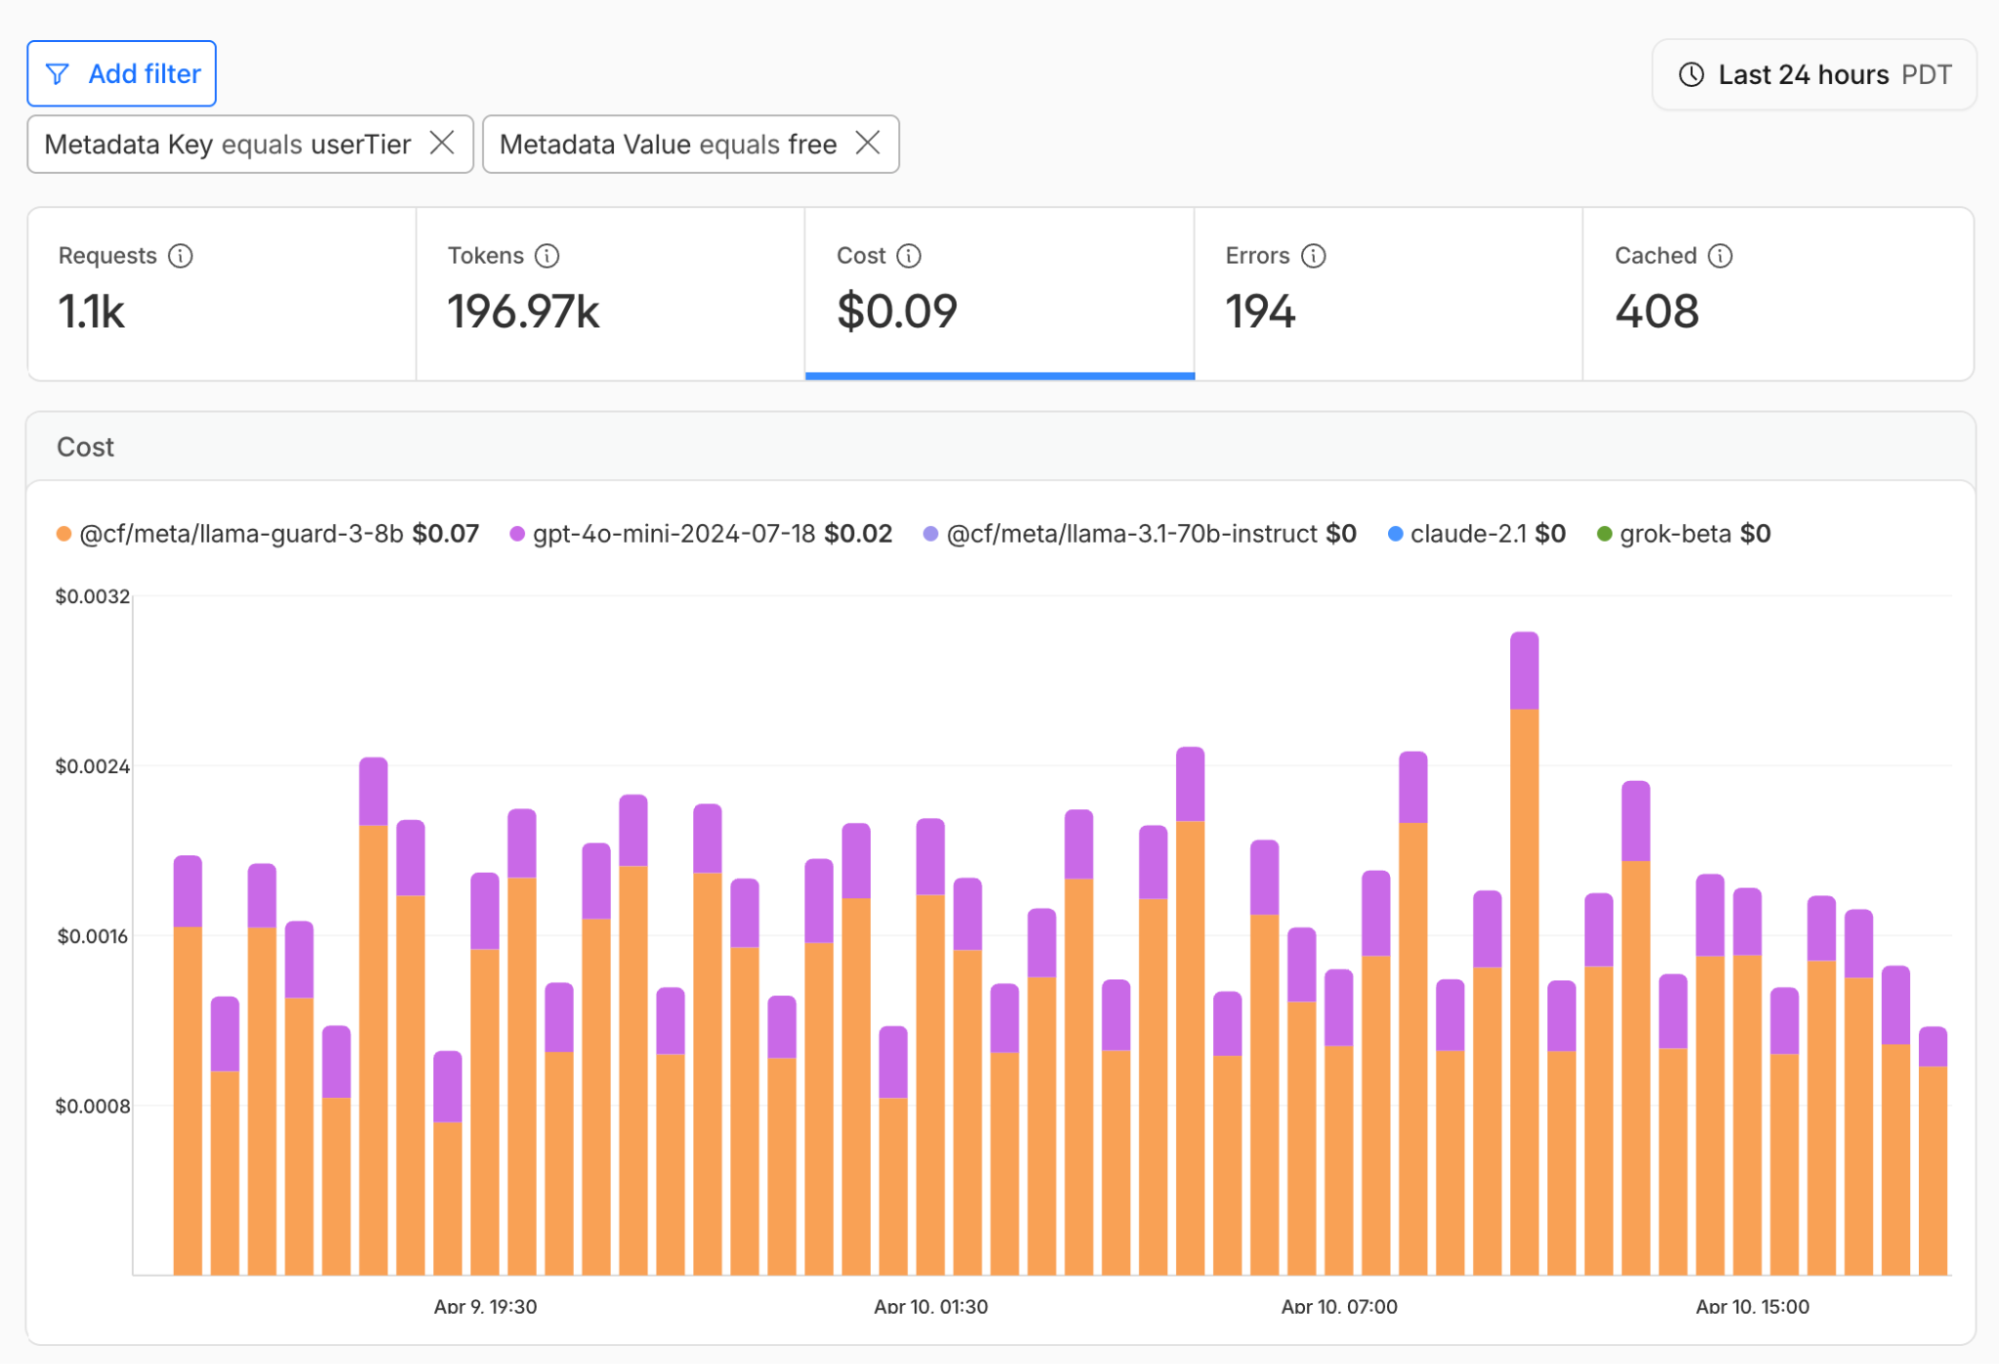
Accessing all your models through one API also means you can manage all your AI spend in one place. Most companies today are calling an average of 3.5 models across multiple providers, which means no one provider is able to give you a holistic view of your AI usage. With AI Gateway, you’ll get one centralized place to monitor and manage AI spend.
By including custom metadata with your requests, you can get a breakdown of your costs on the attributes that you care about most, like spend by free vs. paid users, by individual customers, or by specific workflows in your app.
AI Gateway gives you access to models from all the providers through one API. But sometimes you need to run a model you’ve fine-tuned on your own data or one optimized for your specific use case. For that, we are working on letting users bring their own model to Workers AI.
The overwhelming majority of our traffic comes from dedicated instances for Enterprise customers who are running custom models on our platform, and we want to bring this to more customers. To do this, we leverage Replicate’s Cog technology to help you containerize machine learning models.
Cog is designed to be quite simple: all you need to do is write down dependencies in a cog.yaml file, and your inference code in a Python file. Cog abstracts away all the hard things about packaging ML models, such as CUDA dependencies, Python versions, weight loading, etc.
Example of a predict.py file, which has a function to set up the model and a function that runs when you receive an inference request (a prediction):
from cog import BasePredictor, Path, Input
import torch

class Predictor(BasePredictor):
    def setup(self):
        """Load the model into memory to make running multiple predictions efficient"""
        self.net = torch.load("weights.pth")

    def predict(self,
            image: Path = Input(description="Image to enlarge"),
            scale: float = Input(description="Factor to scale image by", default=1.5)
    ) -> Path:
        """Run a single prediction on the model"""
        # ... pre-processing ...
        output = self.net(input)
        # ... post-processing ...
        return output
Then, you can run cog build to build your container image, and push your Cog container to Workers AI. We will deploy and serve the model for you, which you then access through your usual Workers AI APIs.
We’re working on some big projects to be able to bring this to more customers, like customer-facing APIs and wrangler commands so that you can push your own containers, as well as faster cold starts through GPU snapshotting. We’ve been testing this internally with Cloudflare teams and some external customers who are guiding our vision. If you’re interested in being a design partner with us, please reach out! Soon, anyone will be able to package their model and use it through Workers AI.
The fast path to first token
Using Workers AI models with AI Gateway is particularly powerful if you’re building live agents – where a user’s perception of speed hinges on time to first token or how quickly the agent starts responding, rather than how long the full response takes. Even if total inference is 3 seconds, getting that first token 50ms faster makes the difference between an agent that feels zippy and one that feels sluggish.
Cloudflare’s network of data centers in 330 cities around the world means AI Gateway is positioned close to both users and inference endpoints, minimizing the network time before streaming begins.
Workers AI also hosts open-source models on its public catalog, which now includes large models purpose-built for agents, including Kimi K2.5 and real-time voice models. When you call these Cloudflare-hosted models through AI Gateway, there’s no extra hop over the public Internet since your code and inference run on the same global network, giving your agents the lowest latency possible.
Built for reliability with automatic failover
When building agents, speed is not the only factor that users care about – reliability matters too. Every step in an agent workflow depends on the steps before it. Reliable inference is crucial for agents because one call failing can affect the entire downstream chain.
Through AI Gateway, if you’re calling a model that’s available on multiple providers and one provider goes down, we’ll automatically route to another available provider without you having to write any failover logic of your own.
If you’re building long-running agents with Agents SDK, your streaming inference calls are also resilient to disconnects. AI Gateway buffers streaming responses as they’re generated, independently of your agent’s lifetime. If your agent is interrupted mid-inference, it can reconnect to AI Gateway and retrieve the response without having to make a new inference call or paying twice for the same output tokens. Combined with the Agents SDK’s built-in checkpointing, the end user never notices.
Replicate
The Replicate team has officially joined our AI Platform team, so much so that we don’t even consider ourselves separate teams anymore. We’ve been hard at work on integrations between Replicate and Cloudflare, which include bringing all the Replicate models onto AI Gateway and replatforming the hosted models onto Cloudflare infrastructure. Soon, you’ll be able to access the models you loved on Replicate through AI Gateway, and host the models you deployed on Replicate on Workers AI as well.
Get started
To get started, check out our documentation for AI Gateway or Workers AI. Learn more about building agents on Cloudflare through Agents SDK.
The 7.1 merge window opened on April 12 with the release
of the 7.0 kernel. Since then, 3,855 non-merge changesets have been
pulled into the mainline repository for the next release. This merge
window is thus just getting started, but there has still been a fair amount
of interesting work moving into the mainline.
Version 26.04 of
the KDE Gear collection of applications has been released. Notable changes
include improvements in the Merkuro
Calendar schedule view and event editor, support for threads in the NeoChat Matrix chat client, as well as
the ability to add keyboard shortcuts in the Dolphin file manager “to nearly any
option in any menu, plugin or extension“. See the changelog for
a full list of updates, enhancements, and bug fixes.
Every agent needs search: Coding agents search millions of files across repos. Support agents search customer tickets and internal docs. Even an agent’s memory, its ability to recall past interactions, is fundamentally a search problem. The use cases are different, but the underlying problem is the same: get the right information to the model at the right time.
If you’re building search yourself, you need a vector index, an indexing pipeline that parses and chunks your documents, and something to keep the index up to date when your data changes. If you also need keyword search, that’s a separate index and fusion logic on top. And if each of your agents needs its own searchable context, you’re setting all of that up per agent.
AI Search (formerly AutoRAG) is the plug-and-play search primitive you need. You can dynamically create instances, give it your data, and search — from a Worker, the Agents SDK, or Wrangler CLI. Here’s what we’re shipping:
Hybrid search. Enable both semantic and keyword matching in the same query. Vector search and BM25 run in parallel and results are fused. (The search on our blog is now powered by AI Search. Try the magnifying glass icon to the top right.)
Built-in storage and index. New instances come with their own storage and vector index. Upload files directly to an instance via API and they’re indexed. No R2 buckets to set up, no external data sources to connect first. The new ai_search_namespaces binding lets you create and delete instances at runtime from your Worker, so you can spin up one per agent, per customer, or per language without redeployment.
You can now also attach metadata to documents and use it to boost rankings at query time, and query across multiple instances in a single call.
Now, let’s look at what this means in practice.
In action: Customer Support Agent
Let’s walk through a support agent that searches for two kinds of knowledge: shared product docs, and per-customer history like past resolutions. The product docs are too large to fit in a context window, and each customer’s history grows with every resolved issue, so the agent needs retrieval to find what’s relevant.
Here’s what that looks like with AI Search and the Agents SDK. Start by scaffolding a project:
Let’s say your shared product documentation lives in an R2 bucket called product-doc. You can create a one-off AI Search instance (named product-knowledge) backed by the bucket on the Cloudflare Dashboard within the support namespace:
That’s your shared knowledge base, the docs every agent can reference.
When a customer comes back with a new issue, knowing what’s already been tried saves everyone time. You can track this by creating an AI Search instance per customer. After each resolved issue, the agent saves a summary of what went wrong and how it was fixed. Over time, this builds up a searchable log of past resolutions. You can create instances dynamically using the namespace binding:
// create a per-customer instance when they first show up
await env.SUPPORT_KB.create({
  id: `customer-${customerId}`,
  index_method:{ keyword: true, vector: true }
});
Each instance gets its own built-in storage and vector index — powered by R2 and Vectorize. The instance starts empty and accumulates context over time. Next time the customer comes back, all of it is searchable.
Here’s what the namespace looks like after a few customers:
namespace: "support"
├── product-knowledge     (R2 as source, shared across all agents)
├── customer-abc123       (managed storage, per-customer)
├── customer-def456       (managed storage, per-customer)
└── customer-ghi789       (managed storage, per-customer)
Now the agent itself. It extends AIChatAgent from the Agents SDK and defines two tools. We’re using Kimi K2.5 as the LLM via Workers AI. The model decides when to call the tools based on the conversation:
import { AIChatAgent, type OnChatMessageOptions } from "@cloudflare/ai-chat";
import { createWorkersAI } from "workers-ai-provider";
import { streamText, convertToModelMessages, tool, stepCountIs } from "ai";
import { routeAgentRequest } from "agents";
import { z } from "zod";

export class SupportAgent extends AIChatAgent<Env> {
  async onChatMessage(_onFinish: unknown, options?: OnChatMessageOptions) {
    // the client passes customerId in the request body
    // via the Agent SDK's sendMessage({ body: { customerId } })
    const customerId = options?.body?.customerId;

    // create a per-customer instance when they first show up.
    // each instance gets its own storage and vector index.
    if (customerId) {
      try {
        await this.env.SUPPORT_KB.create({
          id: `customer-${customerId}`,
          index_method: { keyword: true, vector: true }
        });
      } catch {
        // instance already exists
      }
    }

    const workersai = createWorkersAI({ binding: this.env.AI });

    const result = streamText({
      model: workersai("@cf/moonshotai/kimi-k2.5"),
      system: `You are a support agent. Use search_knowledge_base
        to find relevant docs before answering. Search results
        include both product docs and this customer's past
        resolutions — use them to avoid repeating failed fixes
        and to recognize recurring issues. When the issue is
        resolved, call save_resolution before responding.`,
      // this.messages is the full conversation history, automatically
      // persisted by AIChatAgent across reconnects
      messages: await convertToModelMessages(this.messages),
      tools: {
        // tool 1: search across shared product docs AND this
        // customer's past resolutions in a single call
        search_knowledge_base: tool({
          description: "Search product docs and customer history",
          inputSchema: z.object({
            query: z.string().describe("The search query"),
          }),
          execute: async ({ query }) => {
            // always search product docs;
            // include customer history if available
            const instances = ["product-knowledge"];
            if (customerId) {
              instances.push(`customer-${customerId}`);
            }
            return await this.env.SUPPORT_KB.search({
              query: query,
              ai_search_options: {
                // surface recent docs over older ones
                boost_by: [
                  { field: "timestamp", direction: "desc" }
                ],
                // search across both instances at once
                instance_ids: instances
              }
            });
          }
        }),

        // tool 2: after resolving an issue, the agent saves a
        // summary so future agents have full context
        save_resolution: tool({
          description:
            "Save a resolution summary after solving a customer's issue",
          inputSchema: z.object({
            filename: z.string().describe(
              "Short descriptive filename, e.g. 'billing-fix.md'"
            ),
            content: z.string().describe(
              "What the problem was, what caused it, and how it was resolved"
            ),
          }),
          execute: async ({ filename, content }) => {
            if (!customerId) return { error: "No customer ID" };
            const instance = this.env.SUPPORT_KB.get(
              `customer-${customerId}`
            );
            // uploadAndPoll waits until indexing is complete,
            // so the resolution is searchable before the next query
            const item = await instance.items.uploadAndPoll(
              filename, content
            );
            return { saved: true, filename, status: item.status };
          }
        }),
      },
      // cap agentic tool-use loops at 10 steps
      stopWhen: stepCountIs(10),
      abortSignal: options?.abortSignal,
    });

    return result.toUIMessageStreamResponse();
  }
}

// route requests to the SupportAgent durable object
export default {
  async fetch(request: Request, env: Env) {
    return (
      (await routeAgentRequest(request, env)) ||
      new Response("Not found", { status: 404 })
    );
  }
} satisfies ExportedHandler<Env>;
With this, the model decides when to search and when to save. When it searches, it queries product-knowledge and this customer’s past resolutions together. When the issue is resolved, it saves a summary that’s immediately searchable in future conversations.
How AI Search finds what you’re looking for
Under the hood, AI Search runs a multi-step retrieval pipeline, in which every step is configurable.
Hybrid Search: search that understands intent and matches terms
Until now, AI Search only offered vector search. Vector search is great at understanding intent, but it can lose specifics. In a query “ERR_CONNECTION_REFUSED timeout,” the embedding captures the broad concept of connection failures. But the user isn’t looking for general networking docs. They’re looking for the specific document that mentions “ERR_CONNECTION_REFUSED”. Vector search might return results about troubleshooting without ever surfacing the page that contains that exact error string.
Keyword search fills that gap. AI Search now supports BM25, one of the most widely used retrieval scoring functions. BM25 scores documents by how often your query terms appear, how rare those terms are across the entire corpus, and how long the document is. It rewards matches on specific terms, penalizes common filler words, and normalizes for document length. When you search “ERR_CONNECTION_REFUSED timeout”, BM25 finds documents that actually contain “ERR_CONNECTION_REFUSED” as a term. However, BM25 may miss a page about “troubleshooting network connections” even though it may be describing the same problem. That’s where vector search shines, and why you need both.
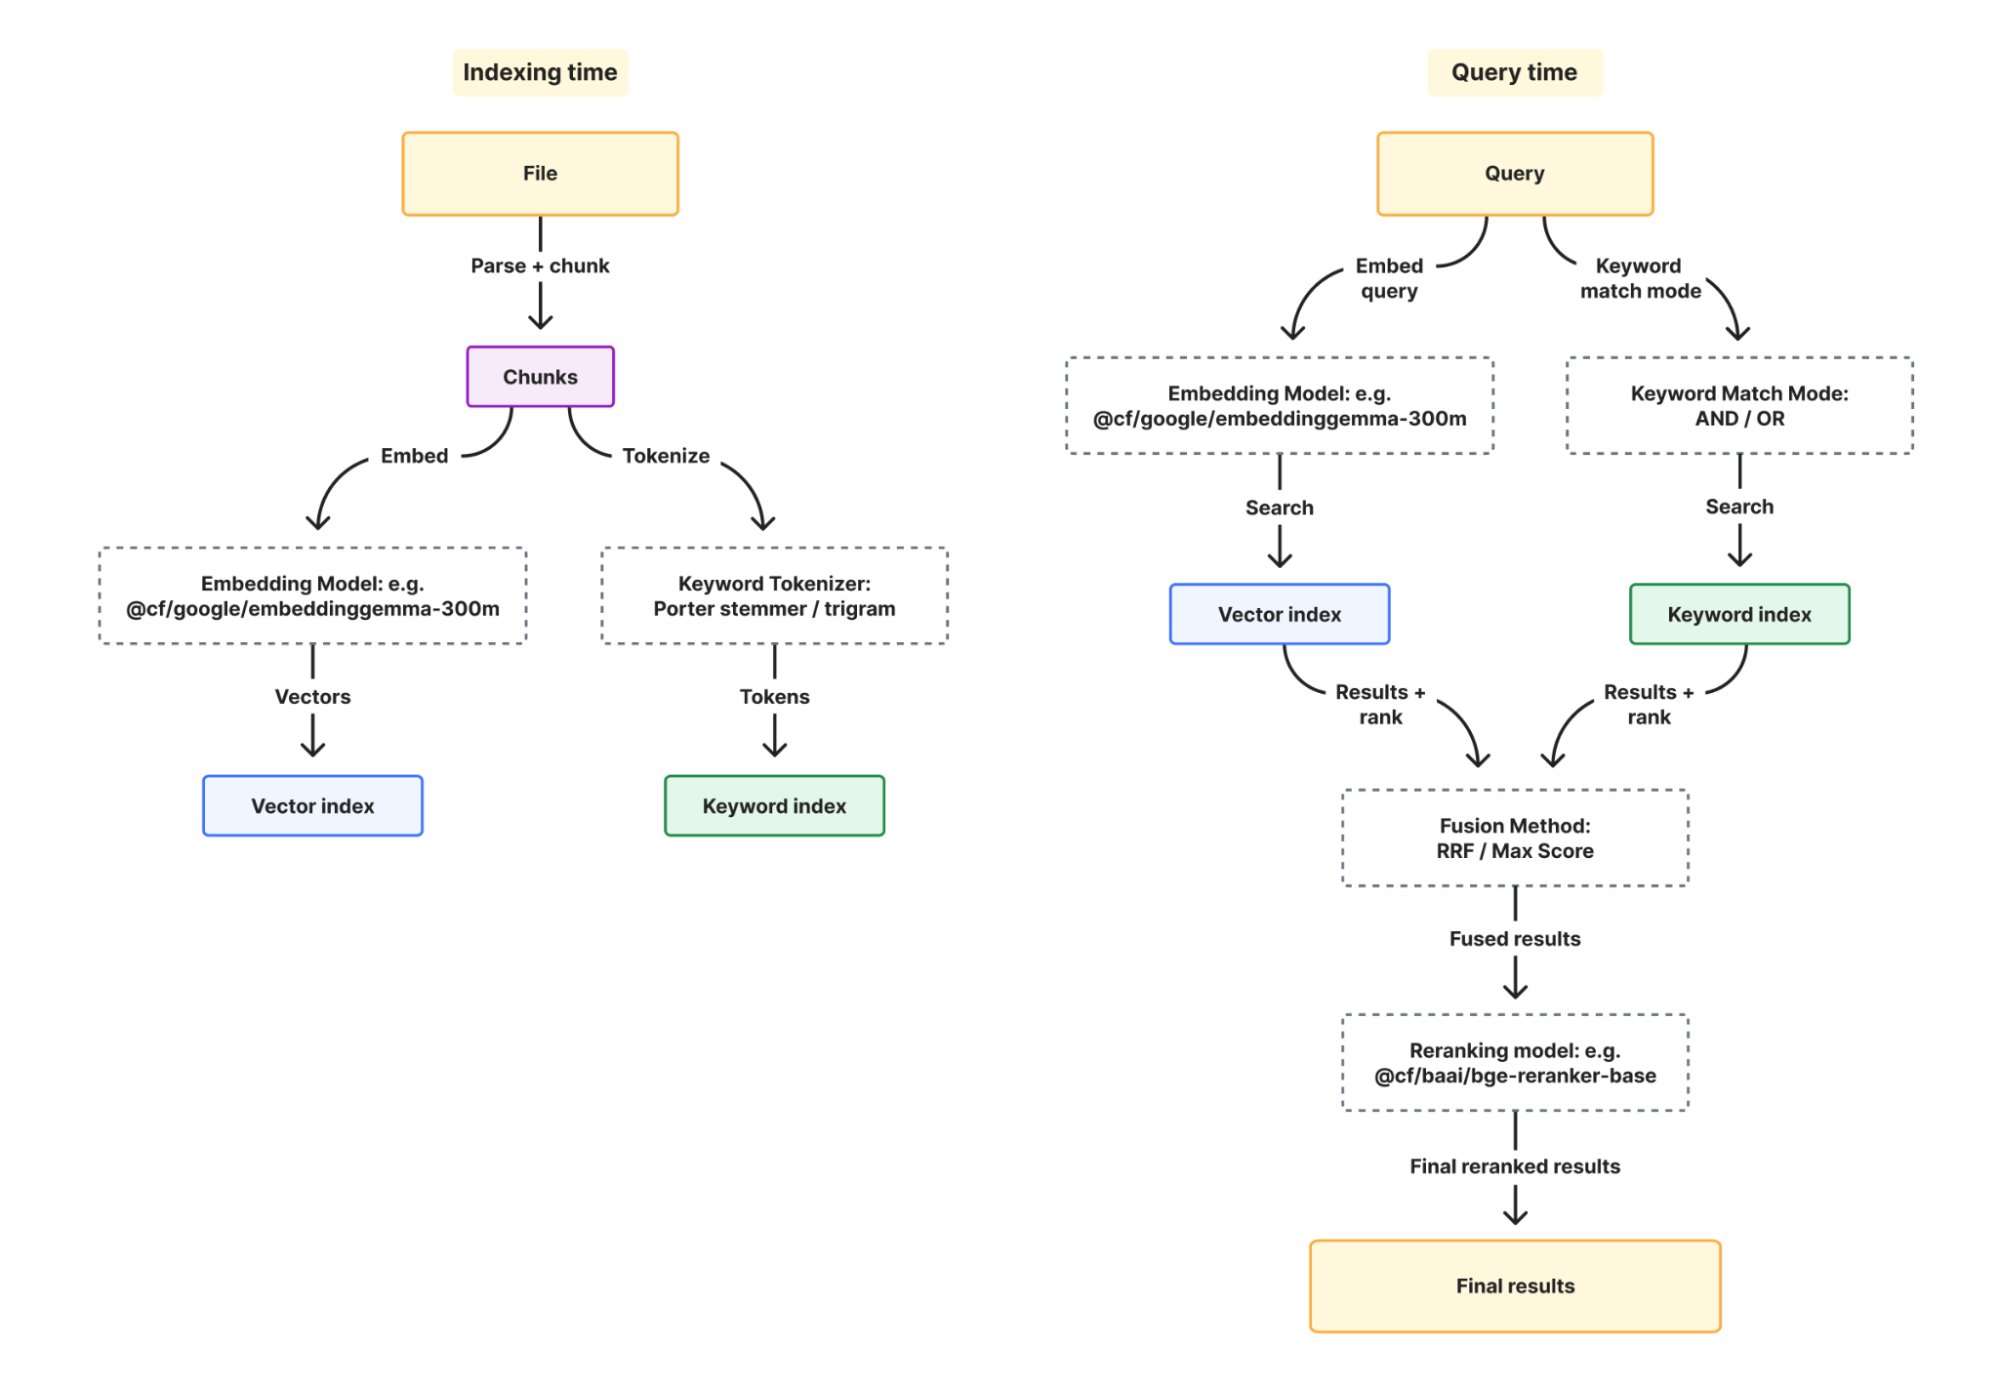
When you enable hybrid search, it runs vector and BM25 in parallel, fuses the results, and optionally reranks them:
Let’s take a look at the new configurations for BM25, and how they come together.
Tokenizer controls how your documents are broken into matchable terms at index time. Porter stemmer (option: porter) stems words so “running” matches “run.” Trigram (option: trigram) matches character substrings so “conf” matches “configuration.” You can use porter for natural language content like docs, and trigram for code where partial matches matter.
Keyword match mode controls which documents are candidates for BM25 scoring at query time. AND requires all query terms to appear in a document, OR includes anything with at least one match.
Fusion controls how vector and keyword results are combined into the final list of results during query time. Reciprocal rank fusion (option: rrf) merges by rank position rather than score, which avoids comparing two incompatible scoring scales, whereas max fusion (option: max) takes the higher score.
(Optional) Reranking adds a cross-encoder pass that re-scores results by evaluating the query and document together as a pair. It can help catch cases where a result has the right terms but isn’t answering the question.
Every option has a sane default when omitted. You have the flexibility to configure what matters whenever you create a new instance:
Retrieval gets you relevant results, but relevance alone isn’t always enough. For example, in a news search, an article from last week and an article from three years ago might both be semantically relevant to “election results,” but most users probably want the recent one. Boosting lets you layer business logic on top of retrieval by nudging rankings based on document metadata.
You can boost on timestamp (built in on every item) or any custom metadata field you define.
In the support agent example, product documentation and customer resolution history live in separate instances by design. But when the agent is answering a question, it needs context from both places at once. Without cross-instance search, you’d make two separate calls and merge the results yourself.
The namespace binding exposes a search() method that handles this for you. Pass an array of instance names and get one ranked list back:
Results are merged and ranked across instances. The agent doesn’t need to know or care that shared docs and customer resolution history live in separate places.
How AI Search instances work
So far we’ve covered how AI Search finds the right results. Now let’s look at how you can create and manage your search instances.
If you used AI Search before this release, you know the setup: create an R2 bucket, link it to an AI Search instance, AI search generates a service API token for you, and you manage the Vectorize index that gets provisioned on your account. Uploading an object requires you to write to R2 and then wait for a sync job to run to have the object indexed.
New instances created now work differently. When you call create(), the instance comes with its own storage and vector index built-in. You can upload a file, the file is sent to index immediately, and you can poll for indexing status all with one uploadAndpoll() API. Once completed, you can search the instance immediately, and there are no external dependencies to wire together.
const instance = env.AI_SEARCH.get("my-instance");

// upload and wait for indexing to complete
const item = await instance.items.uploadAndPoll("faq.md", content, {
  metadata: { category: "onboarding" }
});
console.log(item.status); // "completed"

// immediately search after indexing is completed
const results = await instance.search({
  // alternative way to pass in users' query other than using parameter query
  messages: [{ role: "user", content: "onboarding guide" }],
});
Each instance can also connect to one external data source (an R2 bucket or a website) and run on a sync schedule. It can exist alongside the provided built-in storage. In the support agent example, product-knowledge is backed by an R2 bucket for shared documentation, while each customer’s instance uses built-in storage for context uploaded on the fly.
Namespaces: create search instances at runtime
The ai_search_namespaces is a new binding you can leverage to dynamically create search instances at runtime. It replaces the previous env.AI.autorag() API, which accessed AI Search through the AI binding. The old bindings will continue to work using Workers compatibility dates.
The namespace binding gives you APIs like create(), delete(), list(), and search() at the namespace level. If you’re creating instances dynamically (e.g. per agent, per customer, per tenant), this is the binding to use.
// create an instance
const instance = await env.AI_SEARCH.create({
  id: "my-instance"
});

// delete an instance and all its indexed data
await env.AI_SEARCH.delete("old-instance");
Pricing for new instances
New instances created as of today will get built-in storage and a vector index automatically.
These instances are free to use while AI Search is in open beta with the limits listed below. When using the website as a data source, website crawling using Browser Run (formerly Browser Rendering) is also now a built-in service, meaning that you won’t be billed for it separately. After beta, the goal is to provide unified pricing for AI Search as a single service, rather than billing separately for each underlying component. Workers AI and AI Gateway usage will continue to be billed separately.
We’ll give at least 30 days notice and communicate pricing details before any billing begins.
Limit
Workers Free
Workers Paid
AI Search instances per account
100
5,000
Files per instance
100,000
1M or 500K for hybrid search
Max file size
4MB
4MB
Queries per month
20,000
Unlimited
Maximum pages crawled per day
500
Unlimited
What about existing instances?
If you created instances before this release, they continue to work exactly as they do today. Your R2 buckets, Vectorize indexes, and Browser Run usage remain on your account and are billed as before. We’ll share migration details for existing instances soon.
Get started today
Search is one of the most fundamental things an agent can do. With AI Search, you don’t have to build the infrastructure to make it happen. Create an instance, give it your data, and let your agents search it.
Get started today by running this command to create your first instance:
Cloudflare announced our PlanetScale partnership last September to give Cloudflare Workers direct access to Postgres and MySQL databases for fast, full-stack applications.
Soon, we’re bringing our technologies even closer: you’ll be able to create PlanetScale Postgres and MySQL databases directly from the Cloudflare dashboard and API, and have them billed to your Cloudflare account.
You choose the data storage that fits your Worker application needs and keep a single system for billing as a Cloudflare self-serve or enterprise customer. Cloudflare credits like those given in our startup program or Cloudflare committed spend can be used towards PlanetScale databases.
Postgres & MySQL for Workers
SQL relational databases like Postgres and MySQL are a foundation of modern applications. In particular, Postgres has risen in developer popularity with its rich tooling ecosystem (ORMs, GUIs, etc) and extensions like pgvector for building vector search in AI-driven applications. Postgres is the default choice for most developers who need a powerful, flexible, and scalable database to power their applications.
You can already connect your PlanetScale account and create Postgres databases directly from the Cloudflare dashboard for your Workers. Starting next month, a new Cloudflare subscription will bill for new PlanetScale databases direct to your Cloudflare account as a self-serve or enterprise user.
How to create PlanetScale databases via Cloudflare dashboard after your PlanetScale account is connected. Cloudflare billing is coming next month.
With our built-in integration, PlanetScale databases automatically work with Workers using Hyperdrive, our database connectivity service. Hyperdrive service manages database connection pools and query caching to make database queries fast and reliable. You just add a binding to your Worker’s config file:
And start running SQL queries via your Worker with your Postgres client of choice:
import { Client } from "pg";

export default {
  async fetch(request, env, ctx) {

    const client = new Client({ connectionString: env.DATABASE.connectionString });
    await client.connect();

    const result = await client.query("SELECT * FROM pg_tables");
    ...
}
PlanetScale developer experience
PlanetScale was the obvious choice to provide to the Workers community due to it’s unrivaled performance and reliability. Developers can choose from two of the most popular relational databases with Postgres or Vitess MySQL. PlanetScale matches how Cloudflare treats performance and reliability as key features of a developer platform. And with features like query insights and agent driven workflows for improving SQL query performance and branching for deploying code safely, including database changes, the PlanetScale database developer experience is first-class.
Cloudflare users get the exact same PlanetScale database developer experience. Your PlanetScale databases can be deployed directly from Cloudflare with connections managed via Hyperdrive, which already makes your existing regional databases fast with global Workers. This means access to the same PlanetScale database clusters at standard PlanetScale pricing with all features included like query insights and detailed breakdown of usage and costs.
A single node on PlanetScale Postgres starts at $5/month.
Workers placement
With centralized databases, Workers can run right next to your primary database to reduce latency with an explicit placement hint. By default, Workers execute closest to a user request, which adds network latency when querying a central database especially for multiple queries. Instead, you can configure your Worker to execute in the closest Cloudflare data center to your PlanetScale database. In the future, Cloudflare can automatically set a placement hint based on the location of your PlanetScale database and reduce network latency to single digit milliseconds.
{
  "placement": {
    "region": "aws:us-east-1"
  }
}
Coming soon
You can deploy a PlanetScale Postgres database or connect an existing PlanetScale database to Workers today via the Cloudflare dashboard. Everything today is still billed via PlanetScale.
Launching next month, new PlanetScale databases can be billed to your Cloudflare account.
We are building more with our PlanetScale partners, such as Cloudflare API integration, so tell us what you’d like to see next.
Agents have changed how we think about source control, file systems, and persisting state. Developers and agents are generating more code than ever — more code will be written over the next 5 years than in all of programming history — and it’s driven an order-of-magnitude change in the scale of the systems needed to meet this demand. Source control platforms are especially struggling here: they were built to meet the needs of humans, not a 10x change in volume driven by agents who never sleep, can work on several issues at once, and never tire.
We think there’s a need for a new primitive: a distributed, versioned filesystem that’s built for agents first and foremost, and that can serve the types of applications that are being built today.
We’re calling this Artifacts: a versioned file system that speaks Git. You can create repositories programmatically, alongside your agents, sandboxes, Workers, or any other compute paradigm, and connect to it from any regular Git client.
Want to give every agent session a repo? Artifacts can do it. Every sandbox instance? Also Artifacts. Want to create 10,000 forks from a known-good starting point? You guessed it: Artifacts again. Artifacts exposes a REST API and native Workers API for creating repositories, generating credentials, and commits for environments where a Git client isn’t the right fit (i.e. in any serverless function).
Artifacts is available in private beta for any developers on the paid Workers plan, and we’re aiming to open this up as a public beta by early May.
// Create a repo
const repo = await env.AGENT_REPOS.create(name)
// Pass back the token & remote to your agent
return { repo.remote, repo.token }
# Clone it and use it like any regular git remote
$ git clone https://x:${TOKEN}@123def456abc.artifacts.cloudflare.net/git/repo-13194.git
That’s it. A bare repo, ready to go, created on the fly, that any git client can operate it against.
And if you want to bootstrap an Artifacts repo from an existing git repository so that your agent can work on it independently and push independent changes, you can do that too with .import():
Check out the documentation to get started, or if you want to understand how Artifacts is being used, how it was built, and how it works under the hood: read on.
Why Git? What’s a versioned file system?
Agents know Git. It’s deep in the training data of most models. The happy path and the edge cases are well known to agents, and code-optimized models (and/or harnesses) are particularly good at using git.
Further, Git’s data model is not only good for source control, but for anything where you need to track state, time travel, and persist large amounts of small data. Code, config, session prompts and agent history: all of these are things (“objects”) that you often want to store in small chunks (“commits”) and be able to revert or otherwise roll back to (“history”).
We could have invented an entirely new, bespoke protocol… but then you have the bootstrap problem. AI models don’t know it, so you have to distribute skills, or a CLI, or hope that users are plugged into your docs MCP… all of that adds friction.
If we can just give agents an authenticated, secure HTTPS Git remote URL and have them operate as if it were a Git repo, though? That turns out to work pretty well. And for non-Git-speaking clients — such as a Cloudflare Worker, a Lambda function, or a Node.js app — we’ve exposed a REST API and (soon) language-specific SDKs. Those clients can also use isomorphic-git, but in many cases a simpler TypeScript API can reduce the API surface needed.
Not just for source control
Artifacts’ Git API might make you think it’s just for source control, but it turns out that the Git API and data model is a powerful way to persist state in a way that allows you to fork, time-travel and diff state for any data.
Inside Cloudflare, we’re using Artifacts for our internal agents: automatically persisting the current state of the filesystem and the session history in a per-session Artifacts repo. This enables us to:
Persist sandbox state without having to provision (and keep) block storage around.
Share sessions with others and allow them to time-travel back through both session (prompt) state and file state, irrespective of whether there were commits to the “actual” repository (source control).
And the best: fork a session from any point, allowing our team to share sessions with a co-worker and have them pick it up from them. Debugging something and want another set of eyes? Send a URL and fork it. Want to riff on an API? Have a co-worker fork it and pick up from where you left off.
We’ve also spoken to teams who want to use Artifacts in cases where the Git protocol isn’t a requirement at all, but the semantics (reverting, cloning, diffing) are. Storing per-customer config as part of your product, and want the ability to roll back? Artifacts can be a good representation of this.
We’re excited to see teams explore the non-Git use-cases around Artifacts just as much as the Git-focused ones.
Under the hood
Artifacts are built on top of Durable Objects. The ability to create millions (or tens of millions+) of instances of stateful, isolated compute is inherent to how Durable Objects work today, and that’s exactly what we needed for supporting millions of Git repos per namespace.
Major League Baseball (for live game fan-out), Confluence Whiteboards, and our own Agents SDK use Durable Objects under the hood at significant scale, and so we’re building this on a primitive that we’ve had in production for some time.
What we did need, however, was a Git implementation that could run on Cloudflare Workers. It needed to be small, as complete as possible, extensible (notes, LFS), and efficient. So we built one in Zig, and compiled it to Wasm.
Why did we use Zig? Three reasons:
The entire git protocol engine is written in pure Zig (no libc), compiled to a ~100KB WASM binary (with room for optimization!). It implements SHA-1, zlib inflate/deflate, delta encoding/decoding, pack parsing, and the full git smart HTTP protocol — all from scratch, with zero external dependencies other than the standard library.
Zig gives us manual control over memory allocation which is important in constrained environments like Durable Objects. The Zig Build System lets us easily share code between the WASM runtime (production) and native builds (testing against libgit2 for correctness verification).
The WASM module communicates with the JS host via a thin callback interface: 11 host-imported functions for storage operations (host_get_object, host_put_object, etc.) and one for streaming output (host_emit_bytes). The WASM side is fully testable in isolation.
Under the hood, Artifacts also uses R2 (for snapshots) and KV (for tracking auth tokens):
How Artifacts works (Workers, Durable Objects, and WebAssembly)
A Worker acts as the front-end, handling authentication & authorization, key metrics (errors, latency) and looking up each Artifacts repository (Durable Object) on the fly.
Specifically:
Files are stored in the underlying Durable Object’s SQLite database.
Durable Object storage has a 2MB max row size, so large Git objects are chunked and stored across multiple rows.
We make use of the sync KV API (state.storage.kv) which is backed by SQLite under the hood.
DOs have ~128MB memory limits: this means we can spawn tens of millions of them (they’re fast and light) but have to work within those limits.
We make heavy use of streaming in both the fetch and push paths, directly returning a `ReadableStream<Uint8Array>` built from the raw WASM output chunks.
We avoid calculating our own git deltas, instead, the raw deltas and base hashes are persisted alongside the resolved object. On fetch, if the requesting client already has the base object, Zig emits the delta instead of the full object, which saves bandwidth and memory.
Support for both v1 and v2 of the git protocol.
We support capabilities including ls-refs, shallow clones (deepen, deepen-since, deepen-relative), and incremental fetch with have/want negotiation.
We have an extensive test suite with conformance tests against git clients and verification tests against a libgit2 server designed to validate protocol support.
On top of this, we have native support for git-notes. Artifacts is designed to be agent-first, and notes enable agents to add notes (metadata) to Git objects. This includes prompts, agent attribution and other metadata that can be read/written from the repo without mutating the objects themselves.
Big repos, big problems? Meet ArtifactFS.
Most repos aren’t that big, and Git is designed to be extremely efficient in terms of storage: most repositories take only a few seconds to clone at most, and that’s dominated by network setup time, auth, and checksumming. In most agent or sandbox scenarios, that’s workable: just clone the repo as the sandbox starts and get to work.
But what about a multi-GB repository and/or repos with millions of objects? How can we clone that repo quickly, without blocking the agent’s ability to get to work for minutes and consuming compute?
A popular web framework (at 2.4GB and with a long history!) takes close to 2 minutes to clone. A shallow clone is faster, but not enough to get down to single digit seconds, and we don’t always want to omit history (agents find it useful).
Can we get large repos down to ~10-15 seconds so that our agent can get to work? Well, yes: with a few tricks.
As part of our launch of Artifacts, we’re open-sourcing ArtifactFS, a filesystem driver designed to mount large Git repos as quickly as possible, hydrating file contents on the fly instead of blocking on the initial clone. It’s ideal for agents, sandboxes, containers and other use cases where startup time is critical. If you can shave ~90-100 seconds off your sandbox startup time for every large repo, and you’re running 10,000 of those sandbox jobs per month: that’s 2,778 sandbox hours saved.
You can think of ArtifactFS as “Git clone but async”:
ArtifactFS runs a blobless clone of a git repository: it fetches the file tree and refs, but not the file contents. It can do that during sandbox startup, which then allows your agent harness to get to work.
In the background, it starts to hydrate (download) file contents concurrently via a lightweight daemon.
It prioritizes files that agents typically want to operate on first: package manifests (package.json, go.mod), configuration files, and code, deprioritizing binary blobs (images, executables and other non-text-files) where possible so that agents can scan the file tree as the files themselves are hydrated.
If a file isn’t fully hydrated when the agent tries to read it, the read will block until it has.
The filesystem does not attempt to “sync” files back to the remote repository: with thousands or millions of objects, that’s typically very slow, and since we’re speaking git, we don’t need to. Your agent just needs to commit and push, as it would with any repository. No new APIs to learn.
Importantly, ArtifactFS works with any Git remote, not just our own Artifacts. If you’re cloning large repos from GitHub, GitLab, or self-hosted Git infrastructure: you can still use ArtifactFS.
What’s coming?
Our release today is just the beta, and we’re already working on a number of features that you’ll see land over the next few weeks:
Expanding the available metrics we expose. Today we’re shipping metrics for key operations counts per namespace, repo and stored bytes per repo, so that managing millions of Artifacts isn’t toilsome.
Support for Event Subscriptions for repo-level events so that we can emit events on pushes, pulls, clones, and forks to any repository within a namespace. This will also allow you to consume events, write webhooks, and use those events to notify end-users, drive lifecycle events within your products, and/or run post-push jobs (like CI/CD).
Native TypeScript, Go and Python client SDKs for interacting with the Artifacts API
Repo-level search APIs and namespace-wide search APIs, e.g. “find all the repos with a package.json file”.
We’re also planning an API for Workers Builds, allowing you to run CI/CD jobs on any agent-driven workflow.
What will it cost me?
We’re still early with Artifacts, but want our pricing to work at agent-scale: it needs to be cost effective to have millions of repos, unused (or rarely used) repos shouldn’t be a drag, and our pricing should match the massively-single-tenant nature of agents.
You also shouldn’t have to think about whether a repo is going to be used or not, whether it’s hot or cold, and/or whether an agent is going to wake it up. We’ll charge you for the storage you consume and the operations (e.g. clones, forks, pushes & pulls) against each repo.
$/unit
Included
Operations
$0.15 per 1,000 operations
First 10k included (per month)
Storage
$0.50/GB-mo
First 1GB included.
Big, busy repos will cost more than smaller, less-often-used repos, whether you have 1,000, 100,000, or 10 million of them.
We’ll also be bringing Artifacts to the Workers Free plan (with some fair limits) as the beta progresses, and we’ll provide updates throughout the beta should this pricing change and ahead of billing any usage.
Where do I start?
Artifacts is launching in private beta, and we expect public beta to be ready in early May (2026, to be clear!). We’ll be allowing customers in progressively over the next few weeks, and you can register interest for the private beta directly.
In the meantime, you can learn more about Artifacts by:
It is no secret that phishing campaigns utilizing various ClickFix techniques have been a commonly used method of social engineering. One of the main reasons for this is simply because they work. You know this and Rapid7 does as well. As a company offering managed detection and response (MDR), our customers expect us to be knowledgeable about and able to detect attacks as common as ClickFix campaigns.
Recently, Rapid7 observed a small grouping of ClickFix events across customers in the EU and US. At the time of discovery, this campaign had very little traction on sites like VirusTotal or within the online security landscape. This campaign was particularly interesting as it appeared to be masquerading as an installer for Claude, an AI tool that has received a considerable amount of attention.
Using Rapid7 InsightIDR detection rules, our SOC analysts were able to detect and respond to the threat, preventing further compromise. This campaign demonstrates the strength Rapid7 customers get from our MDR service, while peeling back the curtain to provide a real-world example on how we operate behind the scenes. In this blog, we will detail a brief technical analysis of the observed threat actor activities and discuss how this serves as an example of the service we aim to provide our MDR customers. The analysis highlights both the multi-step delivery of the payload as well as the work Rapid7 performs when investigating threats.
Observed attacker behavior
On April 9, Rapid7 was alerted to mshta executed on a customer asset using the Windows run utility. The alert was generated by the detection rule Attacker Technique – Remote Payload Execution via Run Utility (shell32.dll). This rule will generate an alert when a suspicious process, such as mshta, is added to the RunMRU registry key. This key is important for the detection of ClickFix campaigns, as it tracks the last 26 commands executed by the Windows run utility. One thing that stuck out about this particular mshta command is that the URL, download-version[.]1-5-8[.]com/claude.msixbundle, appeared to be impersonating an MSIX bundle for the popular AI tool, Claude.
MSIX files are Windows app packages that one would typically see from the Microsoft store, definitely not something you would see being passed as an argument to mshta. While the host was quickly taken down before Rapid7 was able to obtain the claude.msixbundle payload, a copy was obtainable on VirusTotal. Looking at the payload, it does initially appear to be an MSIX bundle. The file header signature, PK, indicates that the file is a ZIP archive and contains a string reference to the MSIX bundle, MicrosoftBing_1.1.37.0_ARM64.msix:
⠀
⠀
Exploring the payload deeper, however, reveals an HTML Application (HTA) embedded within the ZIP archive:
⠀
The Visual Basic script within the HTA file contains a series of obfuscated strings that are deobfuscated with the following VBS function:
⠀
Additionally, one of the functions serves to generate an encoded PowerShell script that will serve as the next step in the chain:
⠀
After the deobfuscation routine is complete, these strings contain references to the required objects and function calls to craft and execute – via ShellExec – the following command:
The encoded PowerShell acts as a staging payload. The script will first generate an MD5 hash value based on the COMPUTERNAMEand USERNAME environment variables. It will then take the first 16 characters of the hash value and use it to craft a URL to pull another, much larger, PowerShell script. The script also contains a string deobfuscation routine that is responsible for crafting the following strings to be passed to various .NET functions:
Assembly
System.Mangement.Automation.AmsiUtils
amsiContext
NonPublic,Static
0x41414141
⠀
The script will then call the deobfuscation routine to craft a call to WriteInt32 in the .NET Marshal library to overwrite the amsiContext field in System.Management.Automation.AmsiUtilswith the value 0x41414141. Once amsiContextis overwritten, the script will download and execute the next stage:
⠀
The URL is hosting yet another PowerShell script containing highly obfuscated strings and a large byte array. Upon execution of the script, the strings decode to contain the necessary .NET types and method calls to create and execute a PowerShell ScriptBlock. This ScriptBlock is derived from the byte array, which is first base64 decoded and then run through a deobfuscation routine:
⠀
This ScriptBlock again contains another series of obfuscated strings and a large byte array containing yet another PowerShell ScriptBlock. Following the execution of the script, the code once again creates and executes a PowerShell ScriptBlock:
⠀
This ScriptBlock culminates in a process injection routine using the .NET interoperability library. The code contains a byte array with encrypted shellcode that gets passed through a XOR routine. The script then obtains handles to the following Windows API calls:
NtAllocateVirtualMemory
Copy
NtProtectVirtualMemory
NtCreateThreadEx
NtWaitForSingleObject
NtFreeVirtualMemory
NtClose
After obtaining the handles, the script crafts delegate functions for the Windows API calls and invokes the delegates to perform the process injection routine:
Importance to Rapid7’s MDR customers
Rapid7 MDR customers receive the security knowledge of our threat intelligence, detection engineering, incident response, and security operations center analysts. Input from all of these sources directly feeds into how we create detections and respond to alerts. Following is an explanation of how we use events like these to further provide and enhance our services for customers.
As previously mentioned, ClickFix activity is not new. Detection engineers in the MDR service know this and build rules to address these techniques, such as the rule that caught the activity discussed in this blog.. Detection rules are created in response to activity observed in incident response, customer requests, activity observed from the SOC, threat intelligence, and observations of the security landscape. Rapid7’s detection engineers work with the SOC to monitor these rules for efficacy. Rules that are primarily used to detect initial compromise, such as the one that alerted on this campaign, are additionally monitored to identify any new campaigns.
Once the campaign is identified, our detection engineers research it to create additional rules. They can also perform retroactive threat hunts across the Rapid7 customer base using IOCs or any new behavioral detections created from researching the campaign. Results from researching campaigns like this one then go on to feed threat intelligence and help inform our detection strategy. This campaign provides a great example of how Rapid7 works on the backend to detect and prevent threats in customer environments.
Mitigation guidance
Monitor the following registry key to watch for potential ClickFix attacks such as the one observed in this case:
While Rapid7 MDR customers were covered by the managed SOC, Rapid7 recommends the following actions for containment:
If the activity is not expected, apply containment and review the user’s browsing history for the source of the command. The initial lure is often presented to the user when they attempt to browse the internet for free downloads (media, software, etc.). In some cases the malicious command may have been copied to the user’s clipboard when visiting the initial webpage, and can be viewed by inspecting the source code of the site. If the infection is successful, an information stealer is often executed as the final payload, meaning that any credentials stored on the infected system should be reset as part of restoration.
MITRE ATT&CK techniques
System Binary Proxy Execution: Mshta
T1218.005
Obfuscated Files or Information: Encrypted/Encoded File
T1027.013
Obfuscated Files or Information: Command Obfuscation
Abstract: As Large Language Models (LLMs) integrate into our social and economic interactions, we need to deepen our understanding of how humans respond to LLMs opponents in strategic settings. We present the results of the first controlled monetarily-incentivised laboratory experiment looking at differences in human behaviour in a multi-player p-beauty contest against other humans and LLMs. We use a within-subject design in order to compare behaviour at the individual level. We show that, in this environment, human subjects choose significantly lower numbers when playing against LLMs than humans, which is mainly driven by the increased prevalence of ‘zero’ Nash-equilibrium choices. This shift is mainly driven by subjects with high strategic reasoning ability. Subjects who play the zero Nash-equilibrium choice motivate their strategy by appealing to perceived LLM’s reasoning ability and, unexpectedly, propensity towards cooperation. Our findings provide foundational insights into the multi-player human-LLM interaction in simultaneous choice games, uncover heterogeneities in both subjects’ behaviour and beliefs about LLM’s play when playing against them, and suggest important implications for mechanism design in mixed human-LLM systems.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.