Security updates for Wednesday

Post Syndicated from jzb original https://lwn.net/Articles/1054167/

Security updates have been issued by AlmaLinux (sssd), Debian (linux-6.1 and python-parsl), Fedora (chezmoi, complyctl, composer, and firefox), Oracle (kernel), Red Hat (buildah, libpq, podman, postgresql, postgresql16, postgresql:13, postgresql:15, and postgresql:16), SUSE (avahi, curl, ffmpeg-4, ffmpeg-7, firefox, istioctl, k6, kubelogin, libmicrohttpd, libpcap-devel, libpng16, libtasn1-6-32bit, matio, ovmf, python-tornado6, python311-Authlib, and teleport), and Ubuntu (angular.js, python-urllib3, and webkit2gtk).

Reducing Cloud Chaos: Rapid7 Partners with ARMO to Deliver Cloud Runtime Security

Post Syndicated from Joel Alcon original https://www.rapid7.com/blog/post/cds-reducing-cloud-chaos-rapid7-partners-with-armo-delivering-cloud-runtime-security

Rapid7 has partnered with ARMO, a leader in cloud infrastructure and application security based on runtime data, to offer Cloud Runtime Security. The new offering, currently in beta, extends our vulnerability and exposure management solution, Exposure Command, into the moment where cloud risk becomes real: while applications and workloads are running. The solution does this with several differentiators that map directly to what security leaders need most: signal accuracy and response speed.

Introducing Rapid7 Cloud Runtime Security

Rapid7 Cloud Runtime Security combines kernel-level observability with AI-powered behavioral analysis to create a continuous, threat-aware defense layer within all cloud environments. 

The solution provides:

  • AI-driven behavioral baselines for container activity. Because services, teams, and software releases create constant change, static policies can quickly become irrelevant and overly noisy. Cloud runtime security augmented by AI helps establish a behavioral baseline of what “normal” looks like for workload activity. This baseline becomes the standard for identifying deviations that indicate active exploits. This becomes even more critical for AI workloads in which runtime is the only place to understand behavior. 

  • Root-cause in every risk finding. When a threat is detected, the platform does not just create noise by firing an alert. Instead, it reconstructs the entire event with root-cause insights by linking application-layer activity (like a SQL injection) to infrastructure-level changes (like a container escape). It also provides a natural-language narrative of the attack, showing exactly what happened, which credentials were used, and which resources were accessed.

  • Connected dots across the entire cloud ecosystem. From cloud and Kubernetes events, clusters APIs, container and workload processes, to individual lines of code, the solution displays the entire attack story. Instead of sifting through siloed, disparate security tools that each present different alerts, teams gain a single source of objective truth for faster forensic analysis.

  • Deep application-layer visibility. Instantly detect and respond to common attacks, including SQL injections, command injections, local file inclusion (LFIs), and server-side request forgery (SSRF) that regular endpoint detection and response (EDR) tools overlook because their visibility is limited to the host and process level.

  • Orchestrated automated response to detected anomalies. Detection is only part of the full battle. Speed is the difference between a contained event and a disruptive, expensive data breach. The solution automatically terminates malicious processes, pauses compromised containers, isolates namespaces, or blocks egress to prevent an attacker’s lateral movement.

Rapid7 Cloud Runtime Security enables orchestrated automated response when anomalies are detected, enabling teams to quickly mobilize and contain threats. 

Security amidst the chaos

Chaos is the natural state of cloud environments, where instances frequently shut down and containers constantly change. In these environments, chaos isn’t a deficiency, but an inherent characteristic of distributed systems. Containers spin up and down constantly, deployments change multiple times per day, images get rebuilt and redeployed, identities and permissions drift, and workloads inherit misconfigurations at scale

Traditional vulnerability management (VM) was designed to protect static, on-prem technology architectures. Periodic scans, CVSS scores, and reactive patching have been effective here, but point-in-time snapshots and reactive remediation strategies collapse in dynamic, highly-distributed cloud environments for the following reasons:

  • Blind spots. Ephemeral cloud resources can spin up, perform a task, and disappear in minutes. If a vulnerable container exists for only 10 minutes between a scheduled scan, traditional VM tools will miss it and an automated attacker script will find and exploit it in seconds.

  • Missing context. Network scanners find CVEs, but they often lack contextual awareness. For instance, a ‘critical’ vulnerability may represent a low risk in a library that exists on an isolated container with no internet access. Conversely, a ‘medium’ vulnerability on a public-facing server with an over-privileged IAM role can be a catastrophic exploit.

  • Misconfigurations. In the cloud, vulnerabilities can live on unpatched software, but also arise from misconfigured systems. Consider a fully patched server that is compromised because of an open S3 bucket or a broad IAM policy. According to Gartner, “through 2026, nonpatchable attack surfaces will grow from less than 10% to more than half of the enterprise’s total exposure, reducing the impact of automated remediation practices1.”

  • AI-driven complexity. AI is accelerating innovation cycles, and as organizations push out more code, AI has introduced several new dimensions to the attack surface.  These can include vulnerabilities that trick LLM models into revealing sensitive data or bypassing security controls.

The new baseline for modern cloud security

As modern cloud environments are constantly changing, security teams need to know in real time when exposures become active threats. Rather than toiling over a ‘high’ or ‘critical’ vulnerability, they prioritize remediation actions based on the paths that lead to compromise. This is because a vulnerability can become a critical exposure when the conditions around it make it reachable, exploitable, and high impact. Savvy security teams use exposure management solutions to assess whether they are likely to get compromised, then lean on cloud runtime platforms to identify, in real-time, whether they are actively compromised. As a result, the best security programs now run on a “two-engine” model:

  • Predictive and preemptive with exposure management. This risk-forecasting layer discovers, prioritizes, and guides action on the exposures most likely to lead to material impact. Organizations utilize exposure management solutions to identify which exposures should be addressed first, the shortest paths to breach, and the remediation activities that most reduce risk.

  • Real-time and proactive with runtime security. This threat-reality layer detects anomalous behavior as it happens and supports immediate containment actions. Organizations use runtime security solutions to assess whether an exposure is actively being exploited, the configuration changes that may have led to the exposure, and the actions that need to be taken to contain the threat.

On their own, each part of the engine is valuable, but exposure management without runtime can cause teams to overlook active threats; runtime without exposure context can drown teams in noisy alerts. Together, these solutions enable teams to prioritize what matters most and respond instantly when it becomes active.

Visit our cloud security pages to learn more about how Rapid7 empowers teams to proactively manage risk, accelerate DevSecOps, and enforce compliance across multi-cloud environments.

1 Gartner, Predicts 2023: Enterprises Must Expand From Threat to Exposure Management, Jeremy D’Hoinne, Pete Shoard, Mitchell Schneider, John Watts, December 2022

Coolest Projects 2026: Opens for entries in January!

Post Syndicated from Helen Gardner original https://www.raspberrypi.org/blog/coolest-projects-2026-opens-for-entries-in-january/

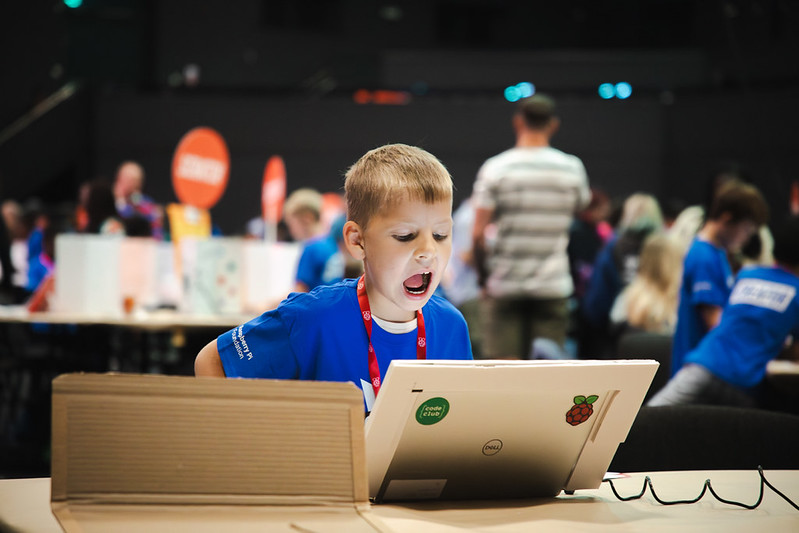
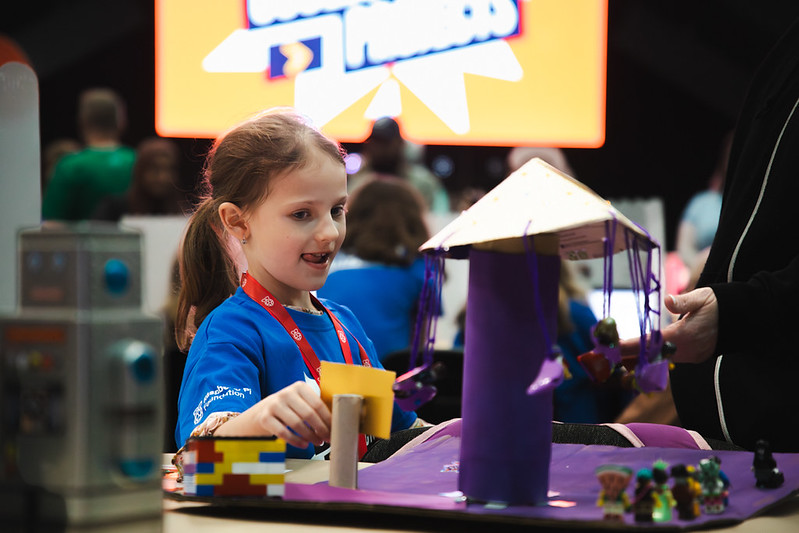
Coolest Projects is our global technology showcase for young people up to age 18. It’s a place where young creators share the brilliant things they’ve made using digital technology — from first-ever Scratch projects and coding for fun experiments to ambitious robotics builds — with a global audience. Everyone who takes part receives certificates and rewards to celebrate their achievements.

What you need to know about Coolest Projects 2026

Coolest Projects is open to any young person, anywhere in the world. Creators can submit their tech projects to our online showcase, explore the global project gallery, and join our special celebration livestream. There are in-person events in some countries for local creators, too (find out more below).

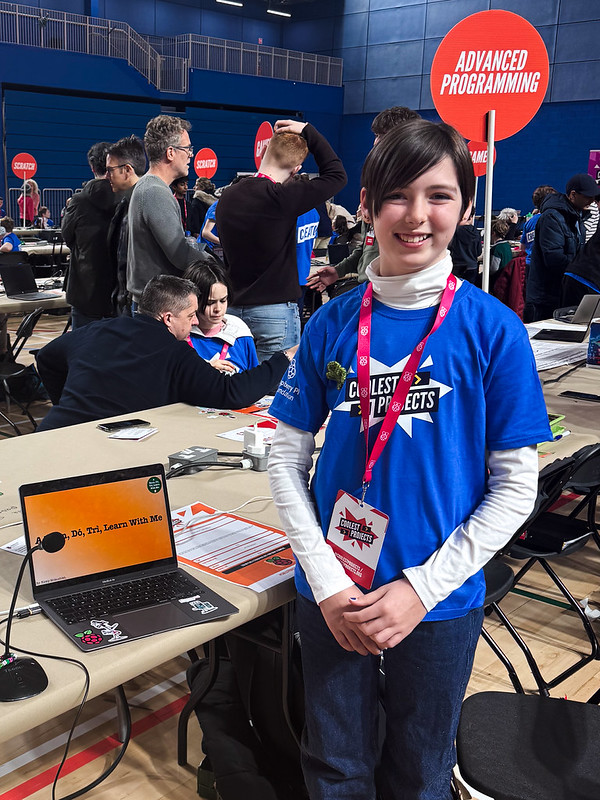
Young learner at Coolest Projects UK

By taking part in Coolest Projects, young people can:

  • Join an international community of digital makers
  • Represent their country on a global stage
  • Receive feedback on their creations
  • Earn certificates to recognise their achievements
  • Celebrate their progress at our livestream event on 24 June 2026

It is completely free to take part in Coolest Projects, and we welcome all kinds of digital technology projects — from first attempts to an ambitious STEM project or advanced build. Projects don’t need to be finished to be submitted. 

Creators can enter a project into one of seven categories: Scratch, Games, Hardware, Web, Mobile Apps, Advanced Programming, and the emergent category of AI.

How Coolest Projects makes a difference

The findings from the Coolest Projects 2025 Impact report offer clear, evidence-based insights into how Coolest Projects builds confidence, creativity, and a sense of belonging for young people around the world. In 2025, almost 12,000 young people from 41 countries took part in Coolest Projects online, a 57% increase on the previous year. This year, we’re excited to welcome even more creators to the Coolest Projects community.

Young learner with her project at Coolest Projects UK

Our annual evaluation shows that Coolest Projects continues to have a powerful impact on young digital creators worldwide. In 2025:

  • 100% of mentors and 72% of young people taking part in the online showcase said their confidence in digital making increased
  • 83% of young people felt inspired to continue learning and participating in computing after taking part
  • 74% of young creators and 100% of mentors said Coolest Projects helped them or their team feel a sense of belonging in computing
  • 80% of surveyed young people said seeing projects from around the world made them feel part of a larger community of makers

Creators told us how proud they felt sharing their work:

“It feels like I’m being noticed!” – Young creator, UK

 “I enjoyed presenting my project and seeing so many creative ideas from others.” – Young creator, India

With many early-stage makers joining for the first time, including 55% of young people at in-person events, Coolest Projects continues to be an accessible entry point into the world of digital creativity.

Young learner at Coolest Projects Ireland

We’re also proud to see growing participation from girls who code, who tell us they value the chance to share their ideas and be inspired by others. At in-person events, girls made up 63% of creators in India, 50% in the US, 39% in Ireland, and 37% in the UK.

Find out more about the incredible creativity and collaboration from mentors and makers worldwide in our 2025 Impact report: rpf.io/cp-impact-2025

How to take part in Coolest Projects

  1. Come up with an idea — or choose something you’ve already made for school or a science fair project. Whether it started as a small classroom task or a personal coding challenge, any tech creation can be part of Coolest Projects. Our projects site offers hundreds of free, step-by-step guides — ideal for beginners, mentors, and anyone looking for engaging STEM activities for kids. The 2025 online gallery is also a great place to find inspiration for your next cool coding project.
  2. Select your category. Our category pages break down each of the seven categories, including our AI category.
  3. Work on the project individually or with friends. Young people can take part individually or in teams of up to five.
  4. Submit it via the Coolest Projects website by 27 May 2026. We encourage creators to take part in both the online showcase and their local in-person event — find the dates below.
  5. See your project showcased in our online gallery.
  6. Join the celebration livestream to discover creations from around the world on 24 June 2026.
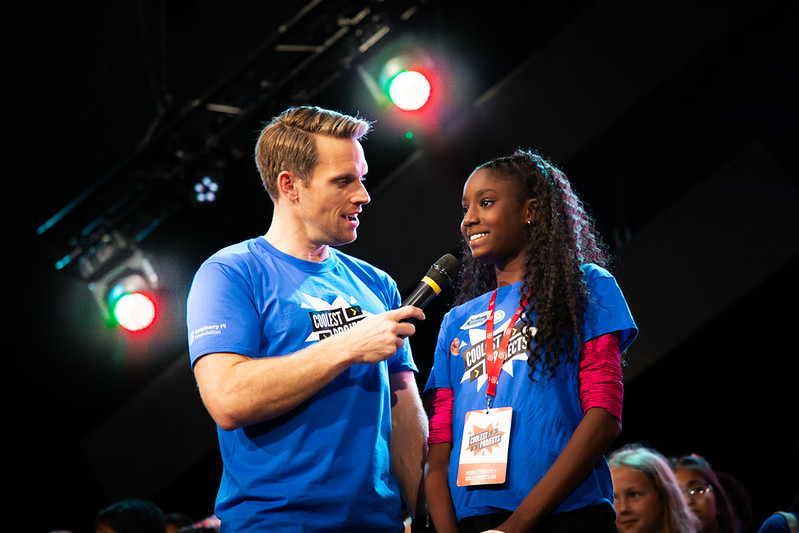
Presenter: Greg Foot interviewing a young learner at Coolest Projects

Group codes for mentors entering multiple projects online

If you’re entering several projects on behalf of your group, you can create a group code to link young people’s projects to your account.

Here’s a quick reminder of how it works:

  • Sign up or log in: Use your Raspberry Pi account or create a new one.
  • Create a group: Add your group details, including name and country.
  • Share your group code: Young people enter the code on their project submission form.
  • Review and submit: View all linked projects in your group dashboard.

There is no limit to the number of young people who can submit through one group code.

If you’d like a full walkthrough, watch our step-by-step group code ‘how-to’ video.

Whether your coders are beginners or experienced digital makers, there are lots of resources to support them. Visit the Coolest Projects guidance page for mentor guides, session plans, and more.

Coolest Projects in-person events in 2026

Alongside the global online showcase, Coolest Projects events will take place in several countries again this year. We encourage creators to take part in both their local in-person event and the global showcase.

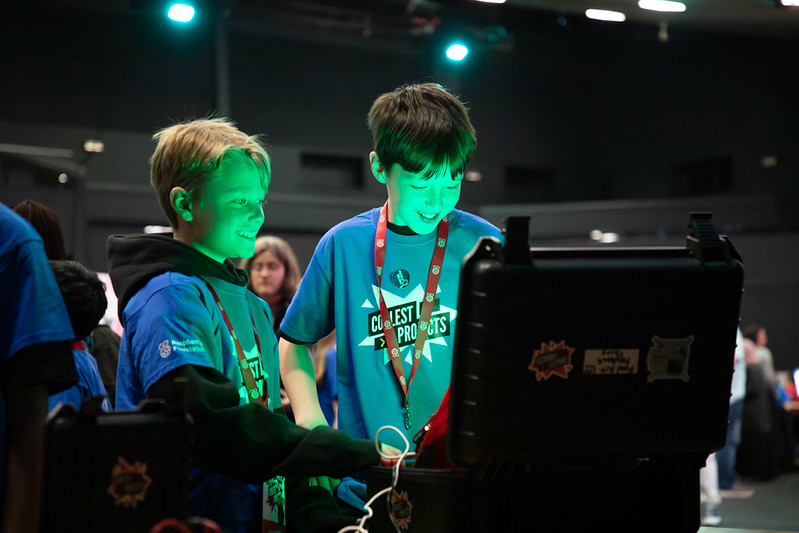
Two young learner testing out a project at Coolest Projects UK

Save the date for:

  • Coolest Projects Belgium – 14 March
  • Coolest Projects Japan – 29 March
  • Coolest Projects USA (Minnesota) – 11 April
  • Coolest Projects Ireland – 25 April
  • Coolest Projects USA (Georgia) – 2 May
  • Coolest Projects UK – 16 May
  • Coolest Projects Sudan (held in Egypt) – 12 August
  • Coolest Projects Nigeria – 29 August

More dates coming soon for:

  • Coolest Projects Canada 
  • Coolest Projects India
  • Coolest Projects Indonesia
  • Coolest Projects Malaysia
  • Coolest Projects South Africa
  • Coolest Projects Sri Lanka

Sign up to the Coolest Projects newsletter to be the first to hear about events near you.

We can’t wait to see what your young people create

Whether your young people already have something they’re excited to share or they’re ready to start something new, Coolest Projects is the perfect place to celebrate their creativity, problem solving, and imagination.

We can’t wait to see the incredible projects they bring to Coolest Projects 2026.

The post Coolest Projects 2026: Opens for entries in January! appeared first on Raspberry Pi Foundation.

Да владееш или да не владееш? Как Западът се върна към началото на XX век

Post Syndicated from Искрен Иванов original https://www.toest.bg/da-vladeesh-ili-da-ne-vladeesh-kak-zapadut-se-vurna-kum-nachaloto-na-xx-vek/

Войната не се заплаща във военно време, сметката винаги идва по-късно.

Да владееш или да не владееш? Как Западът се върна към началото на XX век

С тези думи един от бащите основатели на САЩ Бенджамин Франклин завършва своето историческо писмо от 1755 г., в което апелира към богатите жители на американските колонии да допринасят солидарно за Седемгодишната война между Британската империя и Франция. В продължителната си кореспонденция Франклин ясно предупреждава британската корона, че дългът ѝ е нараснал тройно и че дори при евентуална победа ще се стигне до нови финансови тежести, с които крал Джордж ще трябва да се справя във време, когато американските му владения отдавна вече не са си плащали сметките. 

Да владееш или да не владееш? Как Западът се върна към началото на XX век
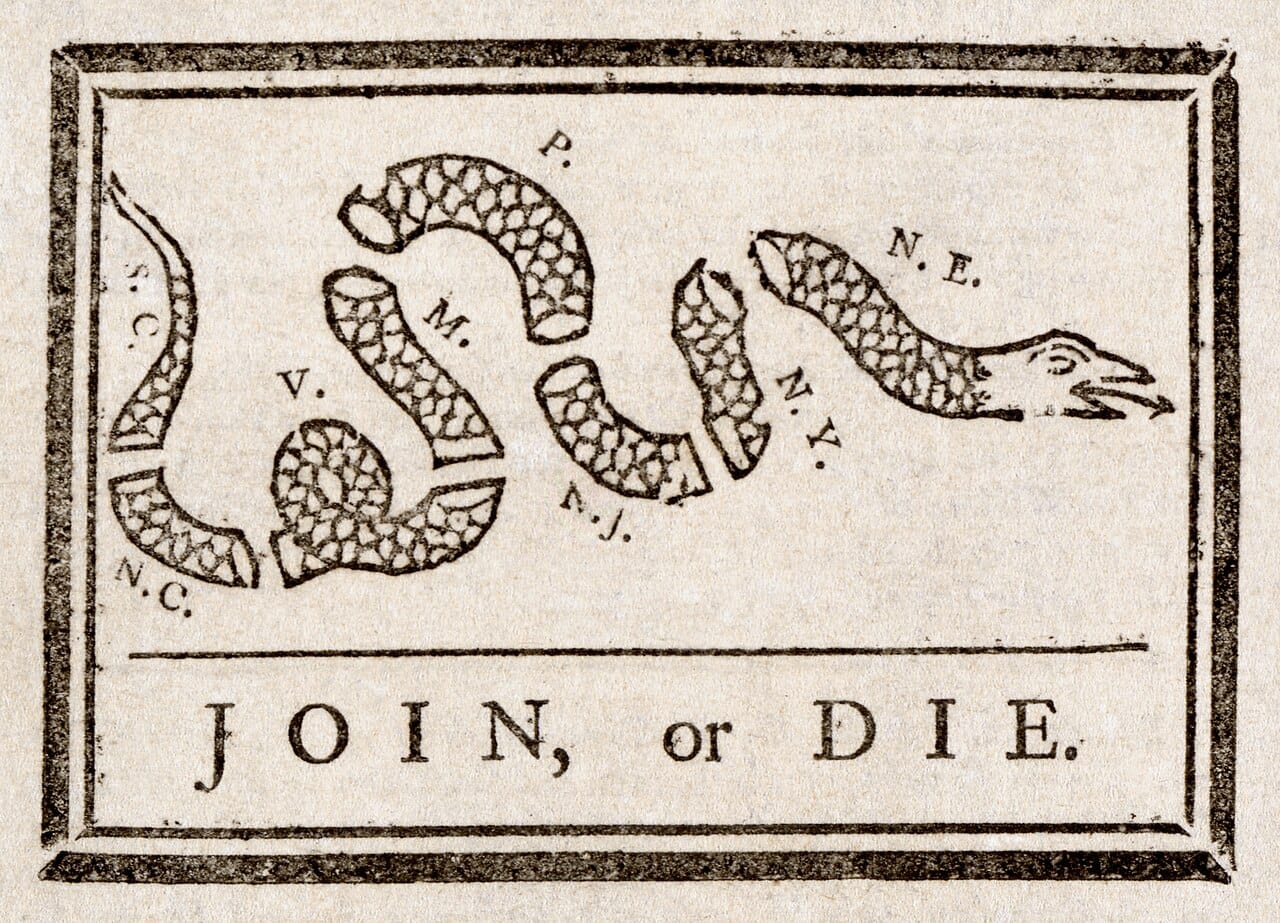
„Присъедини се или умри.“ Политическа карикатура от 1754 г., рисувана от Бенджамин Франклин и публикувана в „Пенсилвания Газет“, Филаделфия. Изображението илюстрира разединението на Тринайсетте колонии по време на Френската и индианска война. Източник: Wikimedia

Въпреки че Седемгодишната война е по-слабо засегнат конфликт в европейската литература, тя е съществен исторически урок за англосаксонците, тъй като представлява вододел в британския колониален модел. Унизителното отношение на британците към коренното население на завладените земи по-късно ще вдъхнови идеологическата трансформация на Франклин – от заявен лоялист на британците той ще се превърне в американски патриот и в един от архитектите на американския политически проект.

Защо, Америка, защо?

Това беше въпросът, който много европейски политици отправиха към американския президент Доналд Тръмп, когато започна военната операция срещу Венецуела и когато американската администрация предяви в доста по-решителен тон апетитите си към най-големия остров в света – Гренландия. Дилемата на Европа обаче сякаш излъчва някакво дълбоко непознаване на начина, по който Америка направлява външната си политика. За останалите глобални актьори, като Китай, Индия и Русия, този въпрос не стои на дневен ред, тъй като те са доста по-наясно с Вашингтон, отколкото с Европа. Както сочи и историята на Студената война, никой не познава толкова добре Вашингтон, колкото Москва, и никой не познава Москва толкова добре, колкото Вашингтон.

Поради липсата на единна външна политика и на отбранителна идентичност Европа в продължение на десетилетия, и то особено след разпада на СССР, не разбира политиката на САЩ. И когато в Белия дом е избран президент, чиято доктрина се базира на стремежа към запазване на американската хегемония, европейците сякаш не успяват да прозрат, че външната политика на Америка винаги е имала една-единствена цел: да гарантира, че САЩ ще бъдат в състояние както да сдържат своите противници, така и да балансират своите съюзници, проправяйки си път към статуса на неоспорим владетел в системата на международните отношения. Към същата цел са се придържали всички президенти на Америка от началото на XX век, било то с твърда или с мека сила.

Важно е да уточним, че отношението на САЩ към европейските им съюзници далеч не е прецедент. В публикуваната Стратегия за национална сигурност на администрацията на Тръмп от 2025 г. съществуват множество догадки каква точно ще е политиката на Америка по време на неговия мандат, но това, което е видимо, е, че доктрината „Тръмп“ на практика модифицира доктрината „Никсън“. 

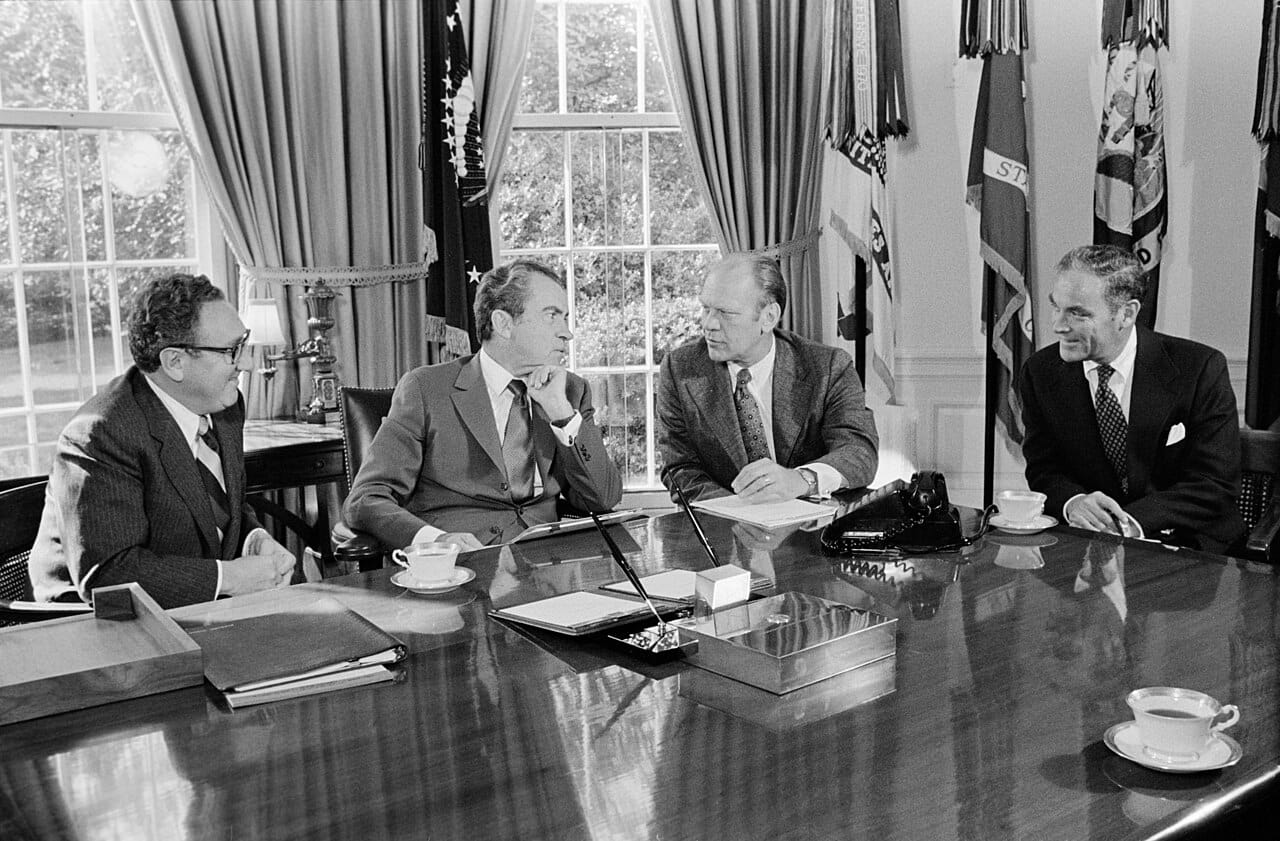
Този цикличен процес в американската външна политика обикновено прожектира пред очите на останалия свят сериала на добрите президенти, желаещи да спасят света от лошите политици, които искат да го разрушат. Показателни са нагласите на Ричард Никсън от началото на мандата му, че САЩ трябва да преговарят от позицията на силния, превръщайки НАТО в буфер за ядрено сдържане пред СССР. В същото време неговата външна политика, възприемайки вплетения от Кисинджър принцип на селективната намеса, категорично се противопоставя на подхода „Кенеди“, който е категоричен в подкрепата си за всички американски съюзници.

Да владееш или да не владееш? Как Западът се върна към началото на XX век
Президентът Ричард Никсън в Овалния кабинет. Кисинджър е най-вляво. 13 октомври 1973 г. Източник: Wikimedia

Тук трябва да си дадем сметка и за още нещо: динамиката на евроатлантическите отношения е пряко обвързана с общия образ на врага, който присъства в представите на САЩ и на европейските им съюзници. Този аспект от възприятията на държавните актьори е ключов, като по този въпрос реалисти, либерали, конструктивисти и дори функционалисти са единодушни, че събирателният образ на опонента е онова, което те мотивира да се защитаваш. По време на Студената война този враг е СССР, а след нейния край и разпадането на Съветския съюз – глобалният тероризъм. 

Оказва се обаче, че тероризмът няма как да бъде напълно изкоренен поради недържавния му характер – предизвикателство, с което нито една политическа теория все още не успява да се справи. С времето радикализацията и различните форми на насилие пуснаха корени на Запад и западните демокрации решиха всеки да се справя с терористите както може. С изчезването, или по-скоро с фрагментирането на този образ на врага евроатлантическото единство постепенно започна да се топи. Процесът се забави значително при администрацията на Обама, която обрисува нов враг – белия екстремизъм, започнал опасно да набира сила в Америка. Не всички европейци обаче бяха готови да купят новия американски продукт, което породи аналогична реакция отляво. 

В тези условия влизането на Байдън в Белия дом беше сантиментален символ, който за последен път припомни на европейските елити, че някога Европа и Америка са били най-близките съюзници. Със завръщането на Тръмп обаче общия образ на врага вече го няма – от една страна, защото САЩ смятат Китай за по-голям проблем от Русия, а от друга, защото за Америка Близкият изток и Пасификът имат по-сериозно значение, отколкото Европа.

Венецуела и Колумбия – новите измерения на доктрината „Тръмп“

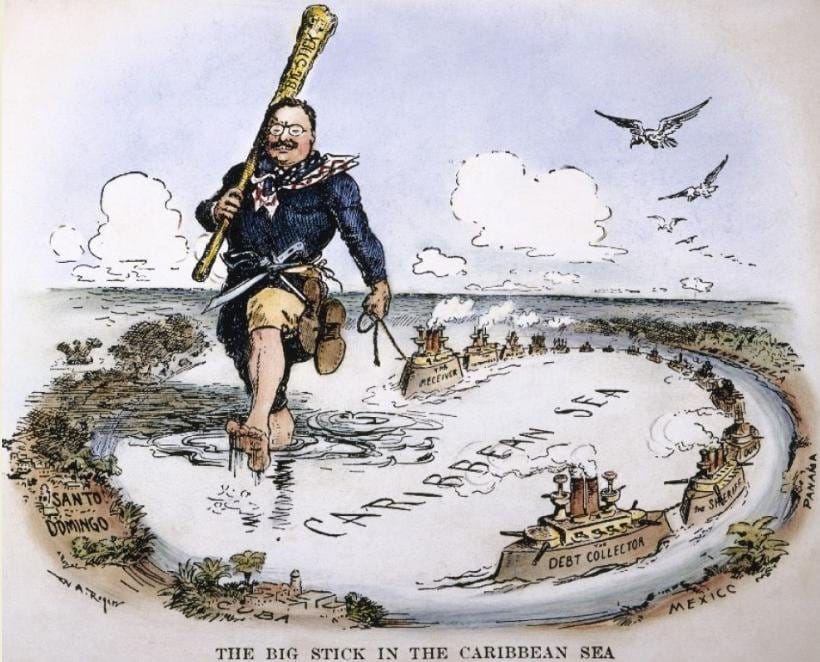
Приетата от администрацията на Тръмп Стратегия за национална сигурност ясно дава да се разбере, че Америка ще воюва само за собствените си интереси. В останалото време ще подпомага индиректно съюзниците си, и то само онези, които споделят нейната визия за света. Погледната от този ъгъл, военната намеса във Венецуела също не трябва да се възприема като уникален момент в историята на САЩ. Тя е проявление на доктрината „Монро“, за която вече говорят всички и с която първоначално Америка заявява на Европа да не се меси в Централна и Латинска Америка. Впоследствие Теодор Рузвелт я развива с т.нар. Политика на голямата тояга, която легитимира правото на САЩ да стопанисват района, намесвайки се в делата на латиноамериканските държави, за да защитят своя интерес. 

Да владееш или да не владееш? Как Западът се върна към началото на XX век
Президентът Рузвелт с „голямата тояга“ в Карибския басейн. 1904 г. Източник: Wikimedia

Тръмп хвърля ръкавицата на останалите държави, които имат претенцията да бъдат Велики сили, със своето допълнение към доктрината, изразяващо готовността на Вашингтон да използва твърда сила, в случай че „задният му двор гори“. До този момент предизвикателството прие единствено Русия, която изпрати свои кораби и подводница, за да защитават петролните танкери, идващи от Венецуела, но и тази операция се превърна във военно фиаско и завърши с пленяването на танкера „Маринера“ от САЩ.

Следва да се отбележи, че действията на Мадуро представляваха реална заплаха за американската национална сигурност. От една страна – защото Венецуела се превърна във важен опорен пункт за външното присъствие на Китай в Латинска Америка. Това се изразяваше най-вече в дългосрочни дипломатически и икономически отношения с режима на Николас Мадуро – под формата на кредити, инфраструктурни проекти и задълбочаваща се финансова зависимост. В този контекст Китай преследва стратегически интереси, свързани с глобалното си икономическо разширяване и с търсенето на политическо влияние в региони, традиционно смятани за зона на американско влияние.

Към това все пак се прибавя и проблемът с наркотрафика към САЩ, който обаче следва да бъде разглеждан по-диференцирано. Мадуро е обвинен от американските власти за участие в кокаинов трафик, основният източник на кокаин в региона остават Колумбия, Боливия и Перу, а Венецуела по-скоро функционира като транзитна територия. В същото време връзката между Китай, организираната престъпност и наркотиците се проявява най-вече по линия на фентанила – чрез китайско производство на прекурсори, които се изкупуват от мексиканските картели, за да се произведе наркотикът, впоследствие достигащ до американския пазар.

Тази комбинация от държавна слабост, международна престъпност и геополитическо съперничество напомня на онова, което в Европа се обозначава като „хибридни заплахи“ – но в случая въздействието е насочено не към общественото мнение, а към общественото здраве и социалната стабилност на Съединените щати.

Втората причина е по-скоро икономическа и се отнася за петролните залежи на Венецуела, които са важни за Америка не само от гледна точка на енергийната ѝ сигурност, но и защото контролът върху тях ще остави Куба и дори Русия (която вече може да разчита само на Иран за петрол) без възможност за редовни доставки на черното злато. Това би довело до ефект на доминото, с чиято помощ режимите в тези държави могат да се разклатят и да се разпаднат сами, без да се налага Америка да разпростира силите си по цялото земно кълбо. Нещо повече, контролът върху Венецуела и нейните партньори би помогнал на САЩ да изолират Китай от глобалната сцена така, както Пекин се опита да загради задния двор на Вашингтон с инвестициите си в Латинска Америка. 

Голямото предизвикателство в целия план на Тръмп обаче остава Мексико, тъй като мексиканците едва ли ще сътрудничат доброволно на американската администрация, а голяма част от политическия и финансов елит на страната много отдавна е свързан с наркокартелите и със стремежа им да разширяват зоната си на влияние към южните щати на Америка.

Гренландската мечта на Тръмп

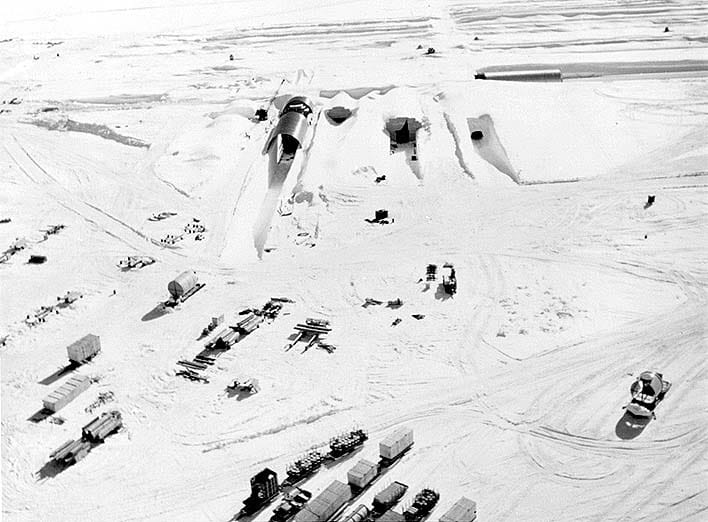
Гренландия има ключово значение за системата на американското ядрено сдържане. Важно е да отбележим интересния исторически факт, че американското военно командване е изпълнявало секретен план за построяването на подземна мрежа от мобилни ядрени установки на острова. Това става през далечната 1960 година и за тези преговори датският премиер Ханс Хансен дори не уведомява своето правителство. Причината е, че когато неговите предшественици съобщават на Комитета по външна политика на Дания за идеите на САЩ, датските политици отказват да подкрепят американския проект за „Гренландската карта“.

В САЩ изчисляват, че ако проектът за изграждането на лагера се осъществи, ще имат възможността не само да нанасят изпреварващи ядрени удари дълбоко в територията на СССР, но и да отговорят на евентуална съветска агресия, без да рискуват атака на своя територия. Когато обаче САЩ и СССР едва не започват ядрена война две години по-късно, по време на Кубинската ракетна криза, суперсилите си дават сметка, че подобни проекти крият прекалено голям риск от ескалация. Така Хрушчов изоставя идеята си да разположи ядрени ракети в Куба, а Кенеди решава да замрази проект „Леден червей“, който предвижда изграждането на секретната ядрена база.

Да владееш или да не владееш? Как Западът се върна към началото на XX век
Въздушна снимка на Camp Century, Гренландия. Източник: Wikimedia

Дали Доналд Тръмп иска да възроди американската ядрена мечта от времето на Студената война, можем само да гадаем. Ясно е единствено, че ако САЩ установят контрол върху Гренландия и разположат там своя военна инфраструктура, американската земя става неуязвима за Русия и Китай както от конвенционална гледна точка, така и по отношение на ядреното сдържане. Тази неуязвимост обаче няма как да бъде проектирана върху европейските съюзници и за тях тя може да послужи единствено като сдържаща гаранция за сигурността им – аналогична на американския ядрен чадър, състоящ се от бойните глави в Европа, които американското военно командване е споделило с НАТО. 

В същото време контролът върху острова ще даде възможност на Америка по всяко време да нанася изпреварващи удари върху Русия и Китай, с чиято помощ да ликвидира критичната им инфраструктура и да се утвърди като хегемон в системата на международните отношения. Тези планове на американската администрация идват на фона на едно отслабено и разединено НАТО, както и при пълното оголване на Западното крайбрежие на САЩ. Причината за последното е сдобиването на Русия с балистични ракети от Северна Корея, които са в състояние да достигнат американска земя.

Насилственото придобиване на острова от САЩ и евентуалната европейска реакция обаче ще положат началото на краткосрочни дезинтеграционни процеси в НАТО. В зависимост от това как ще се осъществи придобиването и каква ще бъде реакцията, отговорност ще носят и двете страни. Защото различията между Америка и Европа вече са толкова големи, колкото сериозна е и геополитическата реалност, че традиционните инструменти за ядрено сдържане и балансът на силите, утвърден след края на Студената война, вече не работят. 

Гренландия може да стане мирно част от Америка само ако датското правителство се съгласи да я продаде или ако формално Дания поиска от САЩ да разширят военното си присъствие в Арктика по силата на съюзническите си ангажименти към Алианса. Тук неизбежно се натрупват и идеологическите различия между съюзниците – във Вашингтон управляват консерватори, а в големите европейски икономики – либерали. Това е може би единственият сигурен успех на руската стратегия – че успява да разедини Запада, както СССР никога не успя.

Преходът от еднополюсен към двуполюсен свят изисква компромиси, за да могат и САЩ, и Европа, за да запазят единството си. Съществуването на Европейския съюз не е под заплаха, стига европейците да успеят да изградят бързо своя система за отбрана, която да гарантира, че Русия няма да нападне Стария континент. 

НАТО, от друга страна, е дългосрочен стратегически проект, но неговата трансформация не трябва да се изключва, тъй като евроатлантическото семейство не е единно по въпросите коя е основната заплаха. Както отбелязва Стивън Уолт, НАТО е колективна система за сигурност, в която съюзниците са споделили своята визия за отбрана, а Америка – ядрения си суверенитет, за да запази Европа цяла.

Това обаче е и най-голямата слабост на Алианса – когато неговите членове нямат обща визия какво ги заплашва, или са толкова объркани, че не могат да различат приятел от враг, НАТО не може да функционира. При такава конфигурация на геополитическата карта в Белия дом управлява президент, който избира подход като на предшествениците си Никсън и Буш-младши, а Русия най-сетне може би ще осъзнае границите на своето геополитическо влияние, отвъд които единствената алтернатива за нея е Трета световна война. Ред е на Китай и Европа да очертаят своите червени линии. Тези проекции могат да бъдат началото на нов оздравителен процес в системата на международните отношения или на поделянето ѝ на сфери на влияние, в които всеки хегемон ще действа с правото на силата.

Patch Tuesday – January 2026

Post Syndicated from Adam Barnett original https://www.rapid7.com/blog/post/em-patch-tuesday-january-2026

Microsoft is publishing 114 vulnerabilities this January 2026 Patch Tuesday. Today’s menu includes just one vulnerability marked as exploited in the wild, as well as two vulnerabilities where Microsoft is aware of public disclosure. There are no critical remote code execution or elevation of privilege vulnerabilities. So far this month, Microsoft has already provided patches to address one browser vulnerability and around a dozen vulnerabilities in open source products, which are not included in the Patch Tuesday count above.

Windows DWM: exploited-in-the-wild information disclosure

The Windows Desktop Windows Manager (DWM) is a high value target for vulnerability researchers and threat actors, and CVE-2026-20805 is the latest in an occasional series of exploited-in-the-wild zero-day vulnerabilities to have emerged from it. DWM is responsible for drawing everything on the display of a Windows system, which means it offers an enticing combination of privileged access and universal availability, since just about any process might need to display something. In this case, exploitation leads to improper disclosure of an ALPC port section address, which is a section of user mode memory where Windows components coordinate various actions between themselves.

The CVSS v3 score of 5.5 evaluates to medium severity, which wouldn’t typically scream “patch me first”, but Microsoft evaluates CVE-2026-20805 as important on their proprietary severity scale, and information disclosure vulnerabilities by their very nature tend to end up with lower CVSS scores, since there’s no direct impact on integrity or availability. Also, Microsoft information disclosure vulnerabilities very rarely end up marked as exploited in the wild; any that do are very likely to be part of a longer exploit chain. In this case, it’s likely that the improperly disclosed memory address gives an attacker a starting point in the hunt for the in-memory address of the DWM process, sidestepping Address Space Layout Randomization (ASLR), and greatly increasing the chance of developing a stable elevation of privilege exploit for DWM rather than a flakey blue screen of death generator.

Windows Agere modem driver: publicly disclosed elevation of privilege

Back in October 2025, Microsoft removed a specific modem driver ltmdm64.sys from all versions of Windows, after it was implicated in CVE-2025-24052, an exploited-in-the-wild elevation of privilege vulnerability. Today sees another couple of modem drivers removed from Windows for a broadly similar reason: Microsoft is aware of functional exploit code for an elevation of privilege vulnerability in a very similar modem driver, tracked as CVE-2023-31096. That’s not a typo; this vulnerability was originally published via MITRE over two years ago, along with a credible public writeup by the original researcher. Today’s Windows patches remove agrsm64.sys and agrsm.sys. All three modem drivers were originally developed by the same now-defunct third party, and have been included in Windows for decades. These driver removals will pass unnoticed for most people, but you might find active modems still in a few contexts, including some industrial control systems.

Two questions remain: how many more legacy modem drivers are still present on a fully-patched Windows asset, and how many more elevation-to-SYSTEM vulnerabilities will emerge from them before Microsoft cuts off attackers who have been enjoying living off the land[line] by exploiting an entire class of dusty old device drivers? Although Microsoft doesn’t claim evidence of exploitation for CVE-2023-31096, the relevant 2023 write-up and the 2025 removal of the other Agere modem driver have provided two strong signals for anyone looking for Windows exploits in the meantime. In case you were wondering, there is no need to have a modem connected; the mere presence of the driver is enough to render an asset vulnerable.

Secure Boot: critical security feature bypass

Today sees the publication of CVE-2026-21265, which is a critical security feature bypass vulnerability affecting Windows Secure Boot. Fifteen years is a very long time indeed in information security, but the clock is running out on the Microsoft root certificates which have been signing essentially everything in the Secure Boot ecosystem since the days of Stuxnet. Microsoft issued replacement certificates back in 2023, alongside CVE-2023-24932 which covered relevant Windows patches as well as subsequent steps to remediate the Secure Boot bypass exploited by the BlackLotus bootkit.

Once the ancient 2011 certificates expire later this year, Windows devices that do not have the new 2023 certificates can no longer receive Secure Boot security fixes. When updating the bootloader and BIOS, it is essential to prepare fully ahead of time for the specific OS and BIOS combination you’re working with, since incorrect remediation steps can lead to an unbootable system.

Microsoft lifecycle update

Visual Studio 2022 LTSC 17.10 reaches end of support today, so now is a good time to upgrade to a newer minor version. Dynamics CRM 2016 (also known as Dynamics 365) also reaches end of life. There are no other significant Microsoft product lifecycle changes this month.

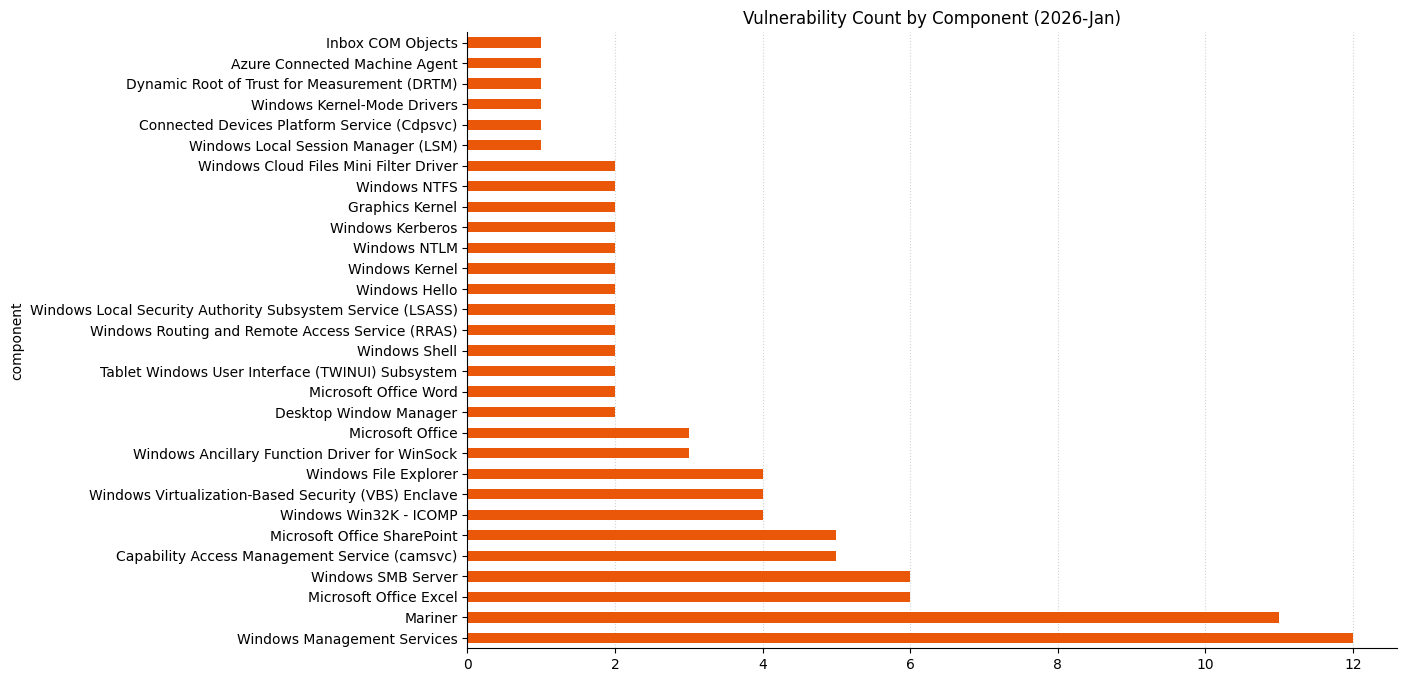
A bar chart showing vulnerability count by component for Microsoft Patch Tuesday 2026-Jan
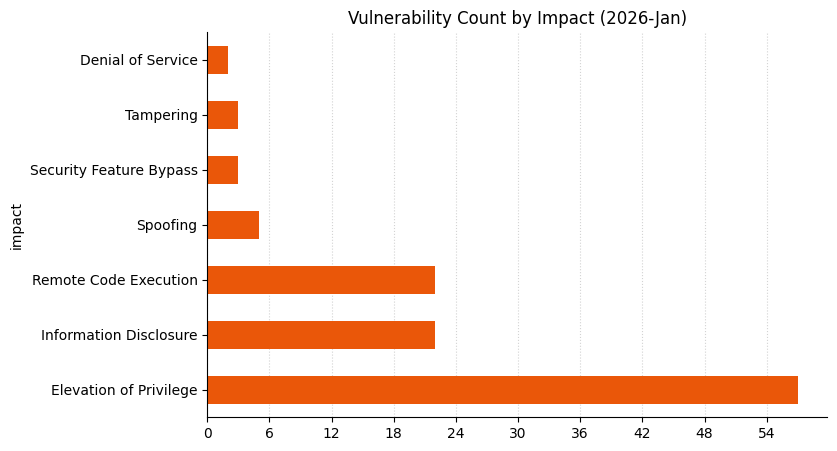
A bar chart showing vulnerability count by impact for Microsoft Patch Tuesday 2026-Jan
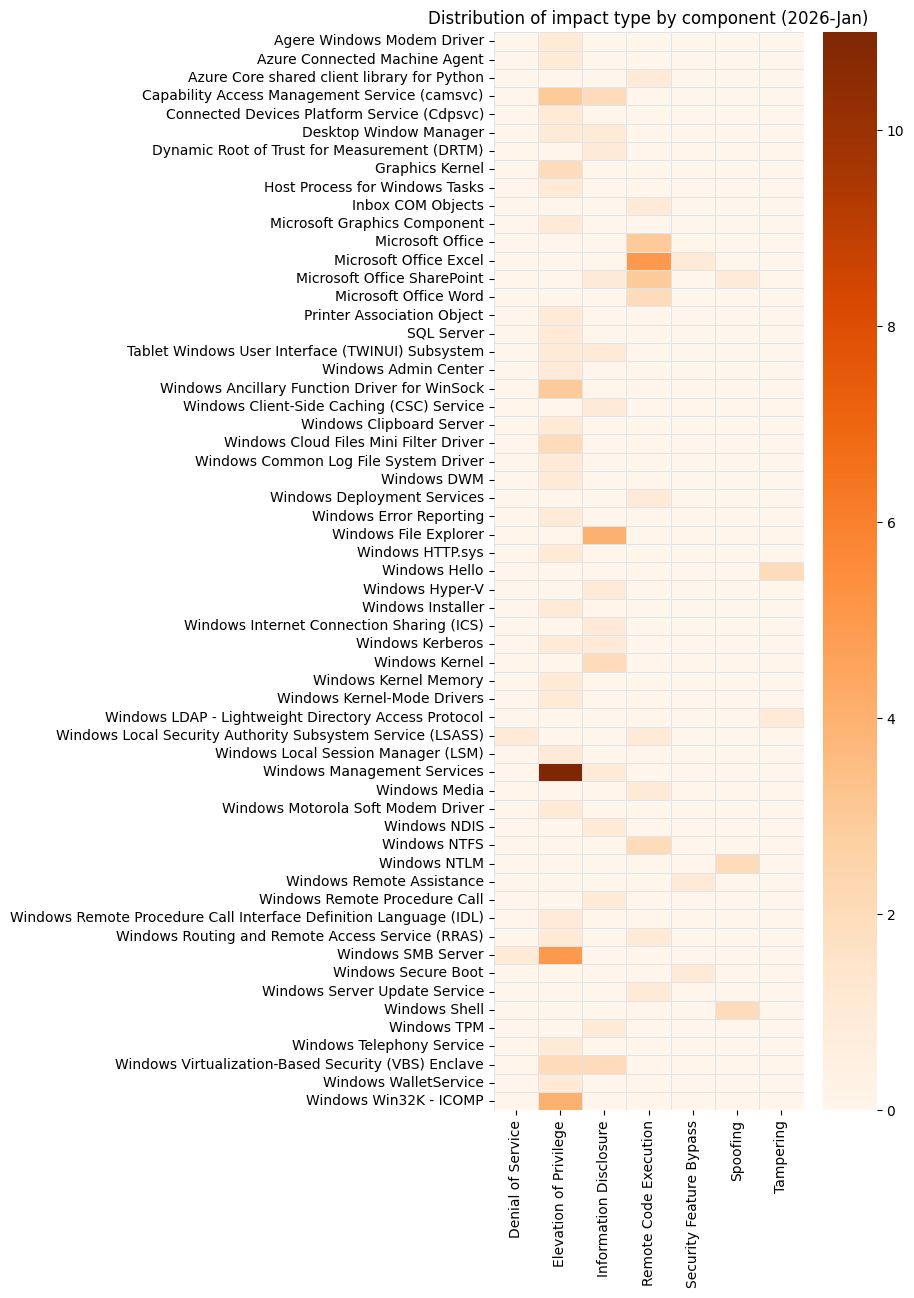
A bar chart showing distribution of impact type by component for Microsoft Patch Tuesday 2026-Jan

Vulnerabilities by Product Family

Azure vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-21224

Azure Connected Machine Agent Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-21226

Azure Core shared client library for Python Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.5

CVE-2026-20965

Windows Admin Center Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.5

Developer Tools vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-21219

Inbox COM Objects (Global Memory) Remote Code Execution Vulnerability

Exploitation Unlikely

No

7.0

ESU vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-20805

Desktop Window Manager Information Disclosure Vulnerability

Exploitation Detected

No

5.5

CVE-2026-20847

Microsoft Windows File Explorer Spoofing Vulnerability

Exploitation Unlikely

No

6.5

CVE-2023-31096

MITRE: CVE-2023-31096 Windows Agere Soft Modem Driver Elevation of Privilege Vulnerability

Exploitation More Likely

Yes

7.8

CVE-2026-20925

NTLM Hash Disclosure Spoofing Vulnerability

Exploitation Less Likely

No

6.5

CVE-2026-20872

NTLM Hash Disclosure Spoofing Vulnerability

Exploitation Less Likely

No

6.5

CVE-2026-20821

Remote Procedure Call Information Disclosure Vulnerability

Exploitation Unlikely

No

6.2

CVE-2026-21265

Secure Boot Certificate Expiration Security Feature Bypass Vulnerability

Exploitation Less Likely

Yes

6.4

CVE-2026-20831

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20860

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20839

Windows Client-Side Caching (CSC) Service Information Disclosure Vulnerability

Exploitation Unlikely

No

5.5

CVE-2026-20940

Windows Cloud Files Mini Filter Driver Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-20820

Windows Common Log File System Driver Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-0386

Windows Deployment Services Remote Code Execution Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20929

Windows HTTP.sys Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20816

Windows Installer Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20849

Windows Kerberos Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20833

Windows Kerberos Information Disclosure Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-20809

Windows Kernel Memory Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20875

Windows Local Security Authority Subsystem Service (LSASS) Denial of Service Vulnerability

Exploitation Less Likely

No

7.5

CVE-2026-20869

Windows Local Session Manager (LSM) Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2024-55414

Windows Motorola Soft Modem Driver Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-20936

Windows NDIS Information Disclosure Vulnerability

Exploitation Unlikely

No

4.3

CVE-2026-20840

Windows NTFS Remote Code Execution Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20922

Windows NTFS Remote Code Execution Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20824

Windows Remote Assistance Security Feature Bypass Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-20828

Windows rndismp6.sys Information Disclosure Vulnerability

Exploitation Less Likely

No

4.6

CVE-2026-20843

Windows Routing and Remote Access Service (RRAS) Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20868

Windows Routing and Remote Access Service (RRAS) Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-20856

Windows Server Update Service (WSUS) Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.1

CVE-2026-20927

Windows SMB Server Denial of Service Vulnerability

Exploitation Unlikely

No

5.3

CVE-2026-20919

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20921

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20926

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20934

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20848

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20834

Windows Spoofing Vulnerability

Exploitation Less Likely

No

4.6

CVE-2026-20931

Windows Telephony Service Elevation of Privilege Vulnerability

Exploitation Unlikely

No

8.0

Microsoft Office vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-20946

Microsoft Excel Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20955

Microsoft Excel Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20956

Microsoft Excel Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20950

Microsoft Excel Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20957

Microsoft Excel Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20949

Microsoft Excel Security Feature Bypass Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20943

Microsoft Office Click-To-Run Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-20953

Microsoft Office Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.4

CVE-2026-20952

Microsoft Office Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.4

CVE-2026-20958

Microsoft SharePoint Information Disclosure Vulnerability

Exploitation Less Likely

No

5.4

CVE-2026-20963

Microsoft SharePoint Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-20951

Microsoft SharePoint Server Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20947

Microsoft SharePoint Server Remote Code Execution Vulnerability

Exploitation Unlikely

No

8.8

CVE-2026-20959

Microsoft SharePoint Server Spoofing Vulnerability

Exploitation Less Likely

No

4.6

CVE-2026-20944

Microsoft Word Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.4

CVE-2026-20948

Microsoft Word Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

SQL Server vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-20803

Microsoft SQL Server Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.2

Windows vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-20815

Capability Access Management Service (camsvc) Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-20830

Capability Access Management Service (camsvc) Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.0

CVE-2026-21221

Capability Access Management Service (camsvc) Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.0

CVE-2026-20835

Capability Access Management Service (camsvc) Information Disclosure Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-20851

Capability Access Management Service (camsvc) Information Disclosure Vulnerability

Exploitation Less Likely

No

6.2

CVE-2026-20805

Desktop Window Manager Information Disclosure Vulnerability

Exploitation Detected

No

5.5

CVE-2026-20871

Desktop Windows Manager Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20814

DirectX Graphics Kernel Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-20836

DirectX Graphics Kernel Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-20962

Dynamic Root of Trust for Measurement (DRTM) Information Disclosure Vulnerability

Exploitation Less Likely

No

4.4

CVE-2026-20941

Host Process for Windows Tasks Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20812

LDAP Tampering Vulnerability

Exploitation Less Likely

No

6.5

CVE-2026-20842

Microsoft DWM Core Library Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-20847

Microsoft Windows File Explorer Spoofing Vulnerability

Exploitation Unlikely

No

6.5

CVE-2023-31096

MITRE: CVE-2023-31096 Windows Agere Soft Modem Driver Elevation of Privilege Vulnerability

Exploitation More Likely

Yes

7.8

CVE-2026-20925

NTLM Hash Disclosure Spoofing Vulnerability

Exploitation Less Likely

No

6.5

CVE-2026-20872

NTLM Hash Disclosure Spoofing Vulnerability

Exploitation Less Likely

No

6.5

CVE-2026-20821

Remote Procedure Call Information Disclosure Vulnerability

Exploitation Unlikely

No

6.2

CVE-2026-21265

Secure Boot Certificate Expiration Security Feature Bypass Vulnerability

Exploitation Less Likely

Yes

6.4

CVE-2026-20826

Tablet Windows User Interface (TWINUI) Subsystem Information Disclosure Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20827

Tablet Windows User Interface (TWINUI) Subsystem Information Disclosure Vulnerability

Exploitation Unlikely

No

5.5

CVE-2026-20829

TPM Trustlet Information Disclosure Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-20811

Win32k Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20920

Win32k Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-20863

Win32k Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-20810

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20831

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20860

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20839

Windows Client-Side Caching (CSC) Service Information Disclosure Vulnerability

Exploitation Unlikely

No

5.5

CVE-2026-20844

Windows Clipboard Server Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.4

CVE-2026-20857

Windows Cloud Files Mini Filter Driver Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-20940

Windows Cloud Files Mini Filter Driver Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-20820

Windows Common Log File System Driver Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20864

Windows Connected Devices Platform Service Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-0386

Windows Deployment Services Remote Code Execution Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20817

Windows Error Reporting Service Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20808

Windows File Explorer Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-20823

Windows File Explorer Information Disclosure Vulnerability

Exploitation Unlikely

No

5.5

CVE-2026-20932

Windows File Explorer Information Disclosure Vulnerability

Exploitation Unlikely

No

5.5

CVE-2026-20937

Windows File Explorer Information Disclosure Vulnerability

Exploitation Unlikely

No

5.5

CVE-2026-20939

Windows File Explorer Information Disclosure Vulnerability

Exploitation Unlikely

No

5.5

CVE-2026-20822

Windows Graphics Component Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20804

Windows Hello Tampering Vulnerability

Exploitation Unlikely

No

7.7

CVE-2026-20852

Windows Hello Tampering Vulnerability

Exploitation Less Likely

No

7.7

CVE-2026-20929

Windows HTTP.sys Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20825

Windows Hyper-V Information Disclosure Vulnerability

Exploitation Less Likely

No

4.4

CVE-2026-20816

Windows Installer Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20849

Windows Kerberos Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20833

Windows Kerberos Information Disclosure Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-20818

Windows Kernel Information Disclosure Vulnerability

Exploitation Unlikely

No

6.2

CVE-2026-20838

Windows Kernel Information Disclosure Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-20809

Windows Kernel Memory Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20859

Windows Kernel-Mode Driver Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20875

Windows Local Security Authority Subsystem Service (LSASS) Denial of Service Vulnerability

Exploitation Less Likely

No

7.5

CVE-2026-20854

Windows Local Security Authority Subsystem Service (LSASS) Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.5

CVE-2026-20869

Windows Local Session Manager (LSM) Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-20858

Windows Management Services Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20865

Windows Management Services Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20877

Windows Management Services Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20918

Windows Management Services Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-20923

Windows Management Services Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20924

Windows Management Services Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20861

Windows Management Services Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20866

Windows Management Services Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20867

Windows Management Services Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-20873

Windows Management Services Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20874

Windows Management Services Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20862

Windows Management Services Information Disclosure Vulnerability

Exploitation Unlikely

No

5.5

CVE-2026-20837

Windows Media Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

CVE-2024-55414

Windows Motorola Soft Modem Driver Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-20936

Windows NDIS Information Disclosure Vulnerability

Exploitation Unlikely

No

4.3

CVE-2026-20840

Windows NTFS Remote Code Execution Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20922

Windows NTFS Remote Code Execution Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20824

Windows Remote Assistance Security Feature Bypass Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-20832

Windows Remote Procedure Call Interface Definition Language (IDL) Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20828

Windows rndismp6.sys Information Disclosure Vulnerability

Exploitation Less Likely

No

4.6

CVE-2026-20843

Windows Routing and Remote Access Service (RRAS) Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-20868

Windows Routing and Remote Access Service (RRAS) Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-20856

Windows Server Update Service (WSUS) Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.1

CVE-2026-20927

Windows SMB Server Denial of Service Vulnerability

Exploitation Unlikely

No

5.3

CVE-2026-20919

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20921

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20926

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20934

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20848

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-20834

Windows Spoofing Vulnerability

Exploitation Less Likely

No

4.6

CVE-2026-20931

Windows Telephony Service Elevation of Privilege Vulnerability

Exploitation Unlikely

No

8.0

CVE-2026-20876

Windows Virtualization-Based Security (VBS) Enclave Elevation of Privilege Vulnerability

Exploitation Less Likely

No

6.7

CVE-2026-20938

Windows Virtualization-Based Security (VBS) Enclave Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-20819

Windows Virtualization-Based Security (VBS) Information Disclosure Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-20935

Windows Virtualization-Based Security (VBS) Information Disclosure Vulnerability

Exploitation Less Likely

No

6.2

CVE-2026-20853

Windows WalletService Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.4

CVE-2026-20870

Windows Win32 Kernel Subsystem Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

What came first: the CNAME or the A record?

Post Syndicated from Sebastiaan Neuteboom original https://blog.cloudflare.com/cname-a-record-order-dns-standards/

On January 8, 2026, a routine update to 1.1.1.1 aimed at reducing memory usage accidentally triggered a wave of DNS resolution failures for users across the Internet. The root cause wasn’t an attack or an outage, but a subtle shift in the order of records within our DNS responses.

While most modern software treats the order of records in DNS responses as irrelevant, we discovered that some implementations expect CNAME records to appear before everything else. When that order changed, resolution started failing. This post explores the code change that caused the shift, why it broke specific DNS clients, and the 40-year-old protocol ambiguity that makes the “correct” order of a DNS response difficult to define.

Timeline

All timestamps referenced are in Coordinated Universal Time (UTC).

Time

Description

2025-12-02

The record reordering is introduced to the 1.1.1.1 codebase

2025-12-10

The change is released to our testing environment

2026-01-07 23:48

A global release containing the change starts

2026-01-08 17:40

The release reaches 90% of servers

2026-01-08 18:19

Incident is declared

2026-01-08 18:27

The release is reverted

2026-01-08 19:55

Revert is completed. Impact ends

What happened?

While making some improvements to lower the memory usage of our cache implementation, we introduced a subtle change to CNAME record ordering. The change was introduced on December 2, 2025, released to our testing environment on December 10, and began deployment on January 7, 2026.

How DNS CNAME chains work

When you query for a domain like www.example.com, you might get a CNAME (Canonical Name) record that indicates one name is an alias for another name. It’s the job of public resolvers, such as 1.1.1.1, to follow this chain of aliases until it reaches a final response:

www.example.com → cdn.example.com → server.cdn-provider.com → 198.51.100.1

As 1.1.1.1 traverses this chain, it caches every intermediate record. Each record in the chain has its own TTL (Time-To-Live), indicating how long we can cache it. Not all the TTLs in a CNAME chain need to be the same:

www.example.com → cdn.example.com (TTL: 3600 seconds) # Still cached
cdn.example.com → 198.51.100.1    (TTL: 300 seconds)  # Expired

When one or more records in a CNAME chain expire, it’s considered partially expired. Fortunately, since parts of the chain are still in our cache, we don’t have to resolve the entire CNAME chain again — only the part that has expired. In our example above, we would take the still valid www.example.com → cdn.example.com chain, and only resolve the expired cdn.example.com A record. Once that’s done, we combine the existing CNAME chain and the newly resolved records into a single response.

The logic change

The code that merges these two chains is where the change occurred. Previously, the code would create a new list, insert the existing CNAME chain, and then append the new records:

impl PartialChain {
    /// Merges records to the cache entry to make the cached records complete.
    pub fn fill_cache(&self, entry: &mut CacheEntry) {
        let mut answer_rrs = Vec::with_capacity(entry.answer.len() + self.records.len());
        answer_rrs.extend_from_slice(&self.records); // CNAMEs first
        answer_rrs.extend_from_slice(&entry.answer); // Then A/AAAA records
        entry.answer = answer_rrs;
    }
}

However, to save some memory allocations and copies, the code was changed to instead append the CNAMEs to the existing answer list:

impl PartialChain {
    /// Merges records to the cache entry to make the cached records complete.
    pub fn fill_cache(&self, entry: &mut CacheEntry) {
        entry.answer.extend(self.records); // CNAMEs last
    }
}

As a result, the responses that 1.1.1.1 returned now sometimes had the CNAME records appearing at the bottom, after the final resolved answer.

Why this caused impact

When DNS clients receive a response with a CNAME chain in the answer section, they also need to follow this chain to find out that www.example.com points to 198.51.100.1. Some DNS client implementations handle this by keeping track of the expected name for the records as they’re iterated sequentially. When a CNAME is encountered, the expected name is updated:

;; QUESTION SECTION:
;; www.example.com.        IN    A

;; ANSWER SECTION:
www.example.com.    3600   IN    CNAME  cdn.example.com.
cdn.example.com.    300    IN    A      198.51.100.1

  1. Find records for www.example.com

  2. Encounter www.example.com. CNAME cdn.example.com

  3. Find records for cdn.example.com

  4. Encounter cdn.example.com. A 198.51.100.1

When the CNAME suddenly appears at the bottom, this no longer works:

;; QUESTION SECTION:
;; www.example.com.	       IN    A

;; ANSWER SECTION:
cdn.example.com.    300    IN    A      198.51.100.1
www.example.com.    3600   IN    CNAME  cdn.example.com.

  1. Find records for www.example.com

  2. Ignore cdn.example.com. A 198.51.100.1 as it doesn’t match the expected name

  3. Encounter www.example.com. CNAME cdn.example.com

  4. Find records for cdn.example.com

  5. No more records are present, so the response is considered empty

One such implementation that broke is the getaddrinfo function in glibc, which is commonly used on Linux for DNS resolution. When looking at its getanswer_r implementation, we can indeed see it expects to find the CNAME records before any answers:

for (; ancount > 0; --ancount)
  {
    // ... parsing DNS records ...
    
    if (rr.rtype == T_CNAME)
      {
        /* Record the CNAME target as the new expected name. */
        int n = __ns_name_unpack (c.begin, c.end, rr.rdata,
                                  name_buffer, sizeof (name_buffer));
        expected_name = name_buffer;  // Update what we're looking for
      }
    else if (rr.rtype == qtype
             && __ns_samebinaryname (rr.rname, expected_name)  // Must match!
             && rr.rdlength == rrtype_to_rdata_length (type:qtype))
      {
        /* Address record matches - store it */
        ptrlist_add (list:addresses, item:(char *) alloc_buffer_next (abuf, uint32_t));
        alloc_buffer_copy_bytes (buf:abuf, src:rr.rdata, size:rr.rdlength);
      }
  }

Another notable affected implementation was the DNSC process in three models of Cisco ethernet switches. In the case where switches had been configured to use 1.1.1.1 these switches experienced spontaneous reboot loops when they received a response containing the reordered CNAMEs. Cisco has published a service document describing the issue.

Not all implementations break

Most DNS clients don’t have this issue. For example, systemd-resolved first parses the records into an ordered set:

typedef struct DnsAnswerItem {
        DnsResourceRecord *rr; // The actual record
        DnsAnswerFlags flags;  // Which section it came from
        // ... other metadata
} DnsAnswerItem;


typedef struct DnsAnswer {
        unsigned n_ref;
        OrderedSet *items;
} DnsAnswer;

When following a CNAME chain it can then search the entire answer set, even if the CNAME records don’t appear at the top.

What the RFC says

RFC 1034, published in 1987, defines much of the behavior of the DNS protocol, and should give us an answer on whether the order of CNAME records matters. Section 4.3.1 contains the following text:

If recursive service is requested and available, the recursive response to a query will be one of the following:

– The answer to the query, possibly preface by one or more CNAME RRs that specify aliases encountered on the way to an answer.

While “possibly preface” can be interpreted as a requirement for CNAME records to appear before everything else, it does not use normative key words, such as MUST and SHOULD that modern RFCs use to express requirements. This isn’t a flaw in RFC 1034, but simply a result of its age. RFC 2119, which standardized these key words, was published in 1997, 10 years after RFC 1034.

In our case, we did originally implement the specification so that CNAMEs appear first. However, we did not have any tests asserting the behavior remains consistent due to the ambiguous language in the RFC.

The subtle distinction: RRsets vs RRs in message sections

To understand why this ambiguity exists, we need to understand a subtle but important distinction in DNS terminology.

RFC 1034 section 3.6 defines Resource Record Sets (RRsets) as collections of records with the same name, type, and class. For RRsets, the specification is clear about ordering:

The order of RRs in a set is not significant, and need not be preserved by name servers, resolvers, or other parts of the DNS.

However, RFC 1034 doesn’t clearly specify how message sections relate to RRsets. While modern DNS specifications have shown that message sections can indeed contain multiple RRsets (consider DNSSEC responses with signatures), RFC 1034 doesn’t describe message sections in those terms. Instead, it treats message sections as containing individual Resource Records (RRs).

The problem is that the RFC primarily discusses ordering in the context of RRsets but doesn’t specify the ordering of different RRsets relative to each other within a message section. This is where the ambiguity lives.

RFC 1034 section 6.2.1 includes an example that demonstrates this ambiguity further. It mentions that the order of Resource Records (RRs) is not significant either:

The difference in ordering of the RRs in the answer section is not significant.

However, this example only shows two A records for the same name within the same RRset. It doesn’t address whether this applies to different record types like CNAMEs and A records.

CNAME chain ordering

It turns out that this issue extends beyond putting CNAME records before other record types. Even when CNAMEs appear before other records, sequential parsing can still break if the CNAME chain itself is out of order. Consider the following response:

;; QUESTION SECTION:
;; www.example.com.              IN    A

;; ANSWER SECTION:
cdn.example.com.           3600  IN    CNAME  server.cdn-provider.com.
www.example.com.           3600  IN    CNAME  cdn.example.com.
server.cdn-provider.com.   300   IN    A      198.51.100.1

Each CNAME belongs to a different RRset, as they have different owners, so the statement about RRset order being insignificant doesn’t apply here.

However, RFC 1034 doesn’t specify that CNAME chains must appear in any particular order. There’s no requirement that www.example.com. CNAME cdn.example.com. must appear before cdn.example.com. CNAME server.cdn-provider.com.. With sequential parsing, the same issue occurs:

  1. Find records for www.example.com

  2. Ignore cdn.example.com. CNAME server.cdn-provider.com. as it doesn’t match the expected name

  3. Encounter www.example.com. CNAME cdn.example.com

  4. Find records for cdn.example.com

  5. Ignore server.cdn-provider.com. A 198.51.100.1 as it doesn’t match the expected name

What should resolvers do?

RFC 1034 section 5 describes resolver behavior. Section 5.2.2 specifically addresses how resolvers should handle aliases (CNAMEs):

In most cases a resolver simply restarts the query at the new name when it encounters a CNAME.

This suggests that resolvers should restart the query upon finding a CNAME, regardless of where it appears in the response. However, it’s important to distinguish between different types of resolvers:

  • Recursive resolvers, like 1.1.1.1, are full DNS resolvers that perform recursive resolution by querying authoritative nameservers

  • Stub resolvers, like glibc’s getaddrinfo, are simplified local interfaces that forward queries to recursive resolvers and process the responses

The RFC sections on resolver behavior were primarily written with full resolvers in mind, not the simplified stub resolvers that most applications actually use. Some stub resolvers evidently don’t implement certain parts of the spec, such as the CNAME-restart logic described in the RFC.

The DNSSEC specifications provide contrast

Later DNS specifications demonstrate a different approach to defining record ordering. RFC 4035, which defines protocol modifications for DNSSEC, uses more explicit language:

When placing a signed RRset in the Answer section, the name server MUST also place its RRSIG RRs in the Answer section. The RRSIG RRs have a higher priority for inclusion than any other RRsets that may have to be included.

The specification uses “MUST” and explicitly defines “higher priority” for RRSIG records. However, “higher priority for inclusion” refers to whether RRSIGs should be included in the response, not where they should appear. This provides unambiguous guidance to implementers about record inclusion in DNSSEC contexts, while not mandating any particular behavior around record ordering.

For unsigned zones, however, the ambiguity from RFC 1034 remains. The word “preface” has guided implementation behavior for nearly four decades, but it has never been formally specified as a requirement.

Do CNAME records come first?

While in our interpretation the RFCs do not require CNAMEs to appear in any particular order, it’s clear that at least some widely-deployed DNS clients rely on it. As some systems using these clients might be updated infrequently, or never updated at all, we believe it’s best to require CNAME records to appear in-order before any other records.

Based on what we have learned during this incident, we have reverted the CNAME re-ordering and do not intend to change the order in the future.

To prevent any future incidents or confusion, we have written a proposal in the form of an Internet-Draft to be discussed at the IETF. If consensus is reached on the clarified behavior, this would become an RFC that explicitly defines how to correctly handle CNAMEs in DNS responses, helping us and the wider DNS community navigate the protocol. The proposal can be found at https://datatracker.ietf.org/doc/draft-jabley-dnsop-ordered-answer-section. If you have suggestions or feedback we would love to hear your opinions, most usefully via the DNSOP working group at the IETF.
[$] A high-level quality-of-service interface

Post Syndicated from daroc original https://lwn.net/Articles/1051982/

Quality-of-service (QoS) mechanisms attempt to prioritize some processes (or
network traffic, disk I/O, etc.) over others in order to meet a system’s
performance goals. This is a difficult topic to handle in the world of Linux,
where workloads, hardware, and user expectations vary wildly. Qais Yousef spoke
at the 2025 Linux Plumbers Conference, alongside his collaborators John Stultz,
Steven Rostedt, and Vincent Guittot, about their plans for introducing a
high-level QoS API for Linux in a way that leaves end users in control of its
configuration. The talk focused specifically on a QoS mechanism for the
scheduler, to prioritize access to CPU resources differently for different kinds
of processes.
(slides;
video)

Optimizing storage performance for Amazon EKS on AWS Outposts

Post Syndicated from Arun Kumar original https://aws.amazon.com/blogs/compute/optimizing-storage-performance-for-amazon-eks-on-aws-outposts/

Amazon Elastic Kubernetes Service (Amazon EKS) on AWS Outposts brings the power of managed Kubernetes to your on-premises infrastructure. Use Amazon EKS on Outposts rack to create hybrid cloud deployments that maintain consistent AWS experiences across environments. As organizations increasingly adopt edge computing and hybrid architectures, storage optimization and performance tuning become critical for successful workload deployment.

Outposts extend AWS infrastructure, services, APIs, and tools to virtually any datacenter, co-location space, or on-premises facility. In this blog post you will learn about your storage options and their performance characteristics which is essential for building resilient, high-performing applications using Amazon EKS on Outposts.

Amazon EKS on Outposts deployment options

The following two sections outline the differences between Amazon EKS extended and local cluster deployment options available on Outposts.

Amazon EKS extended cluster architecture

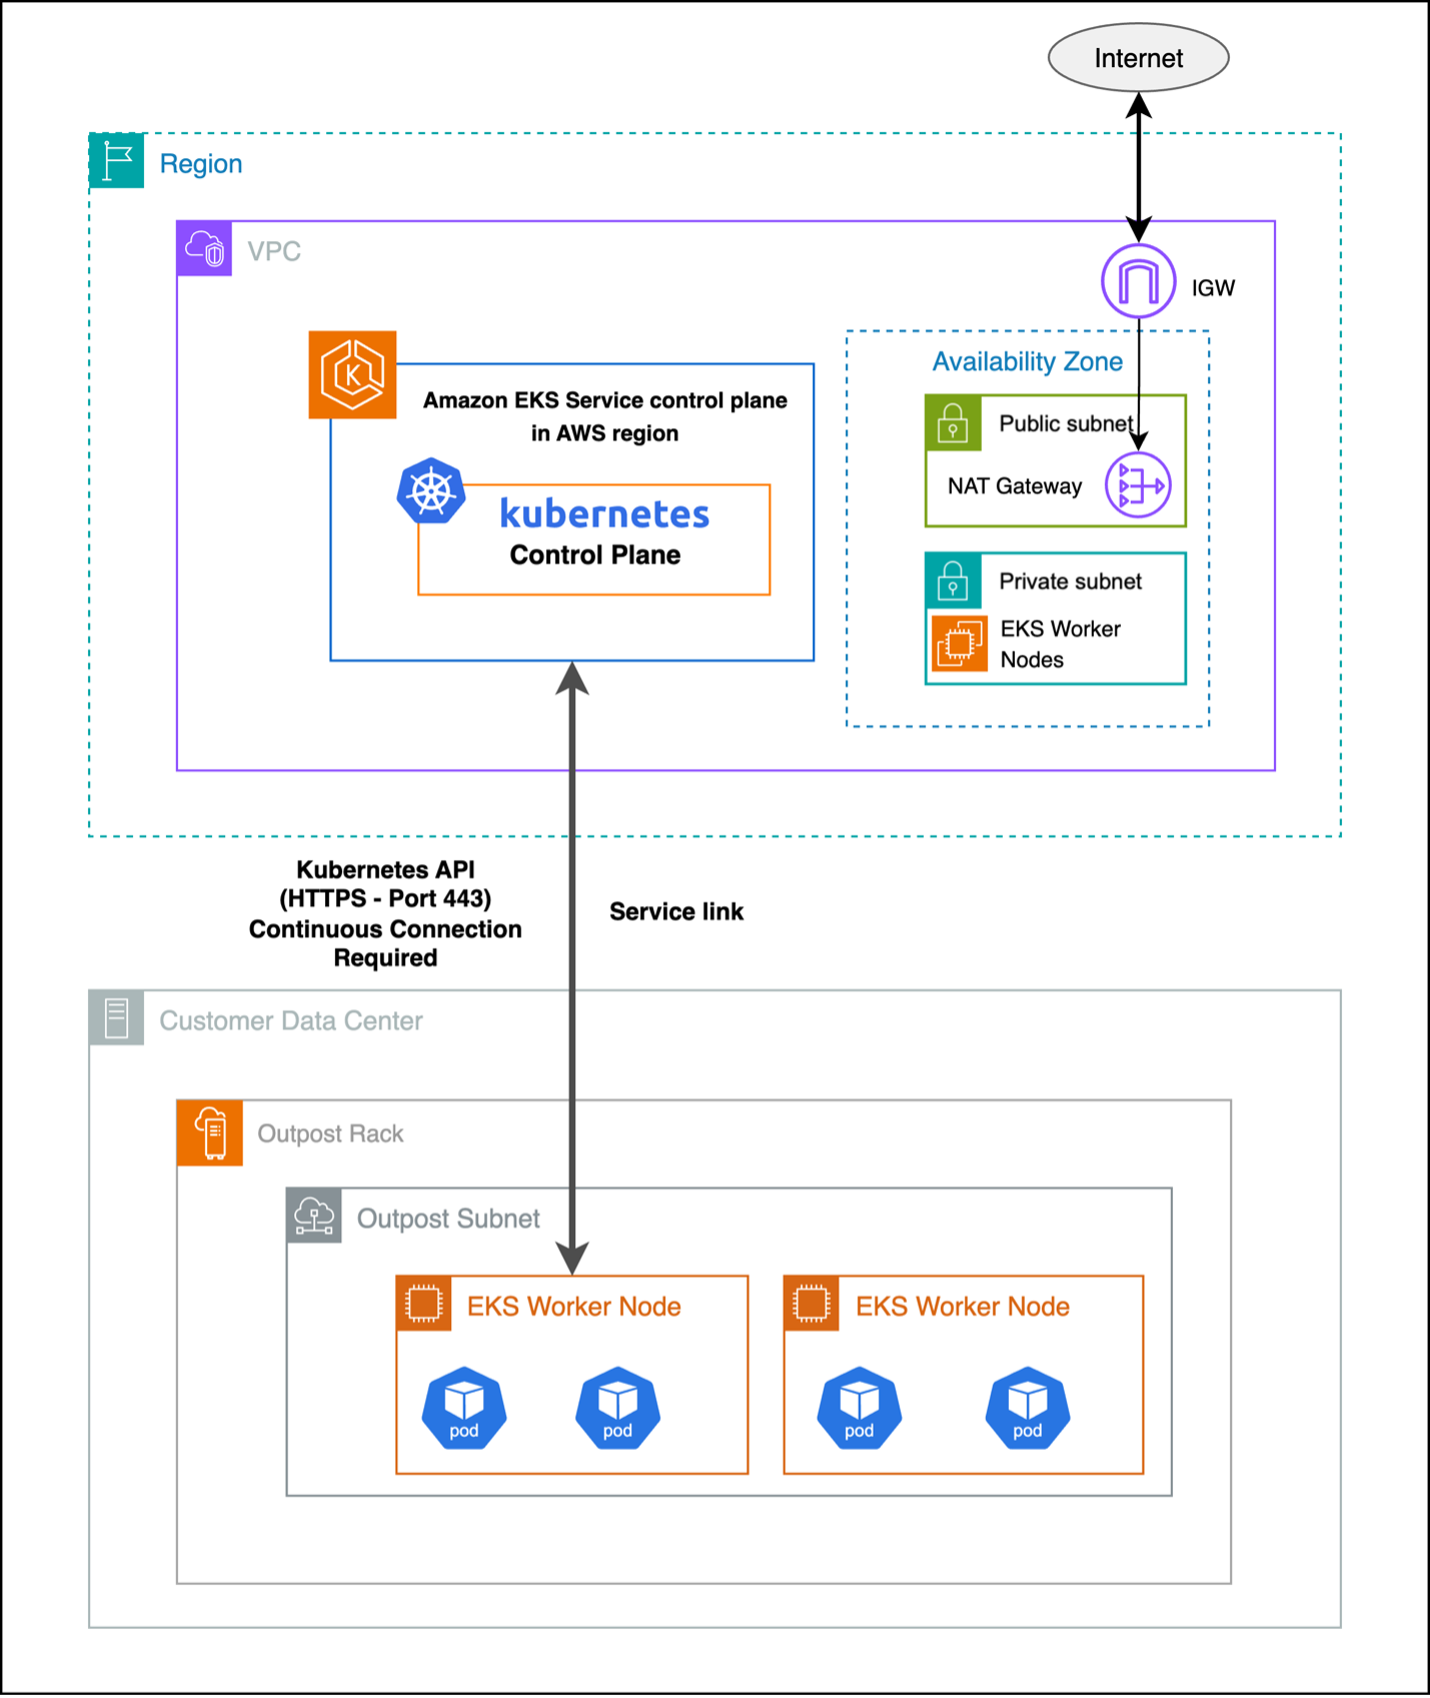
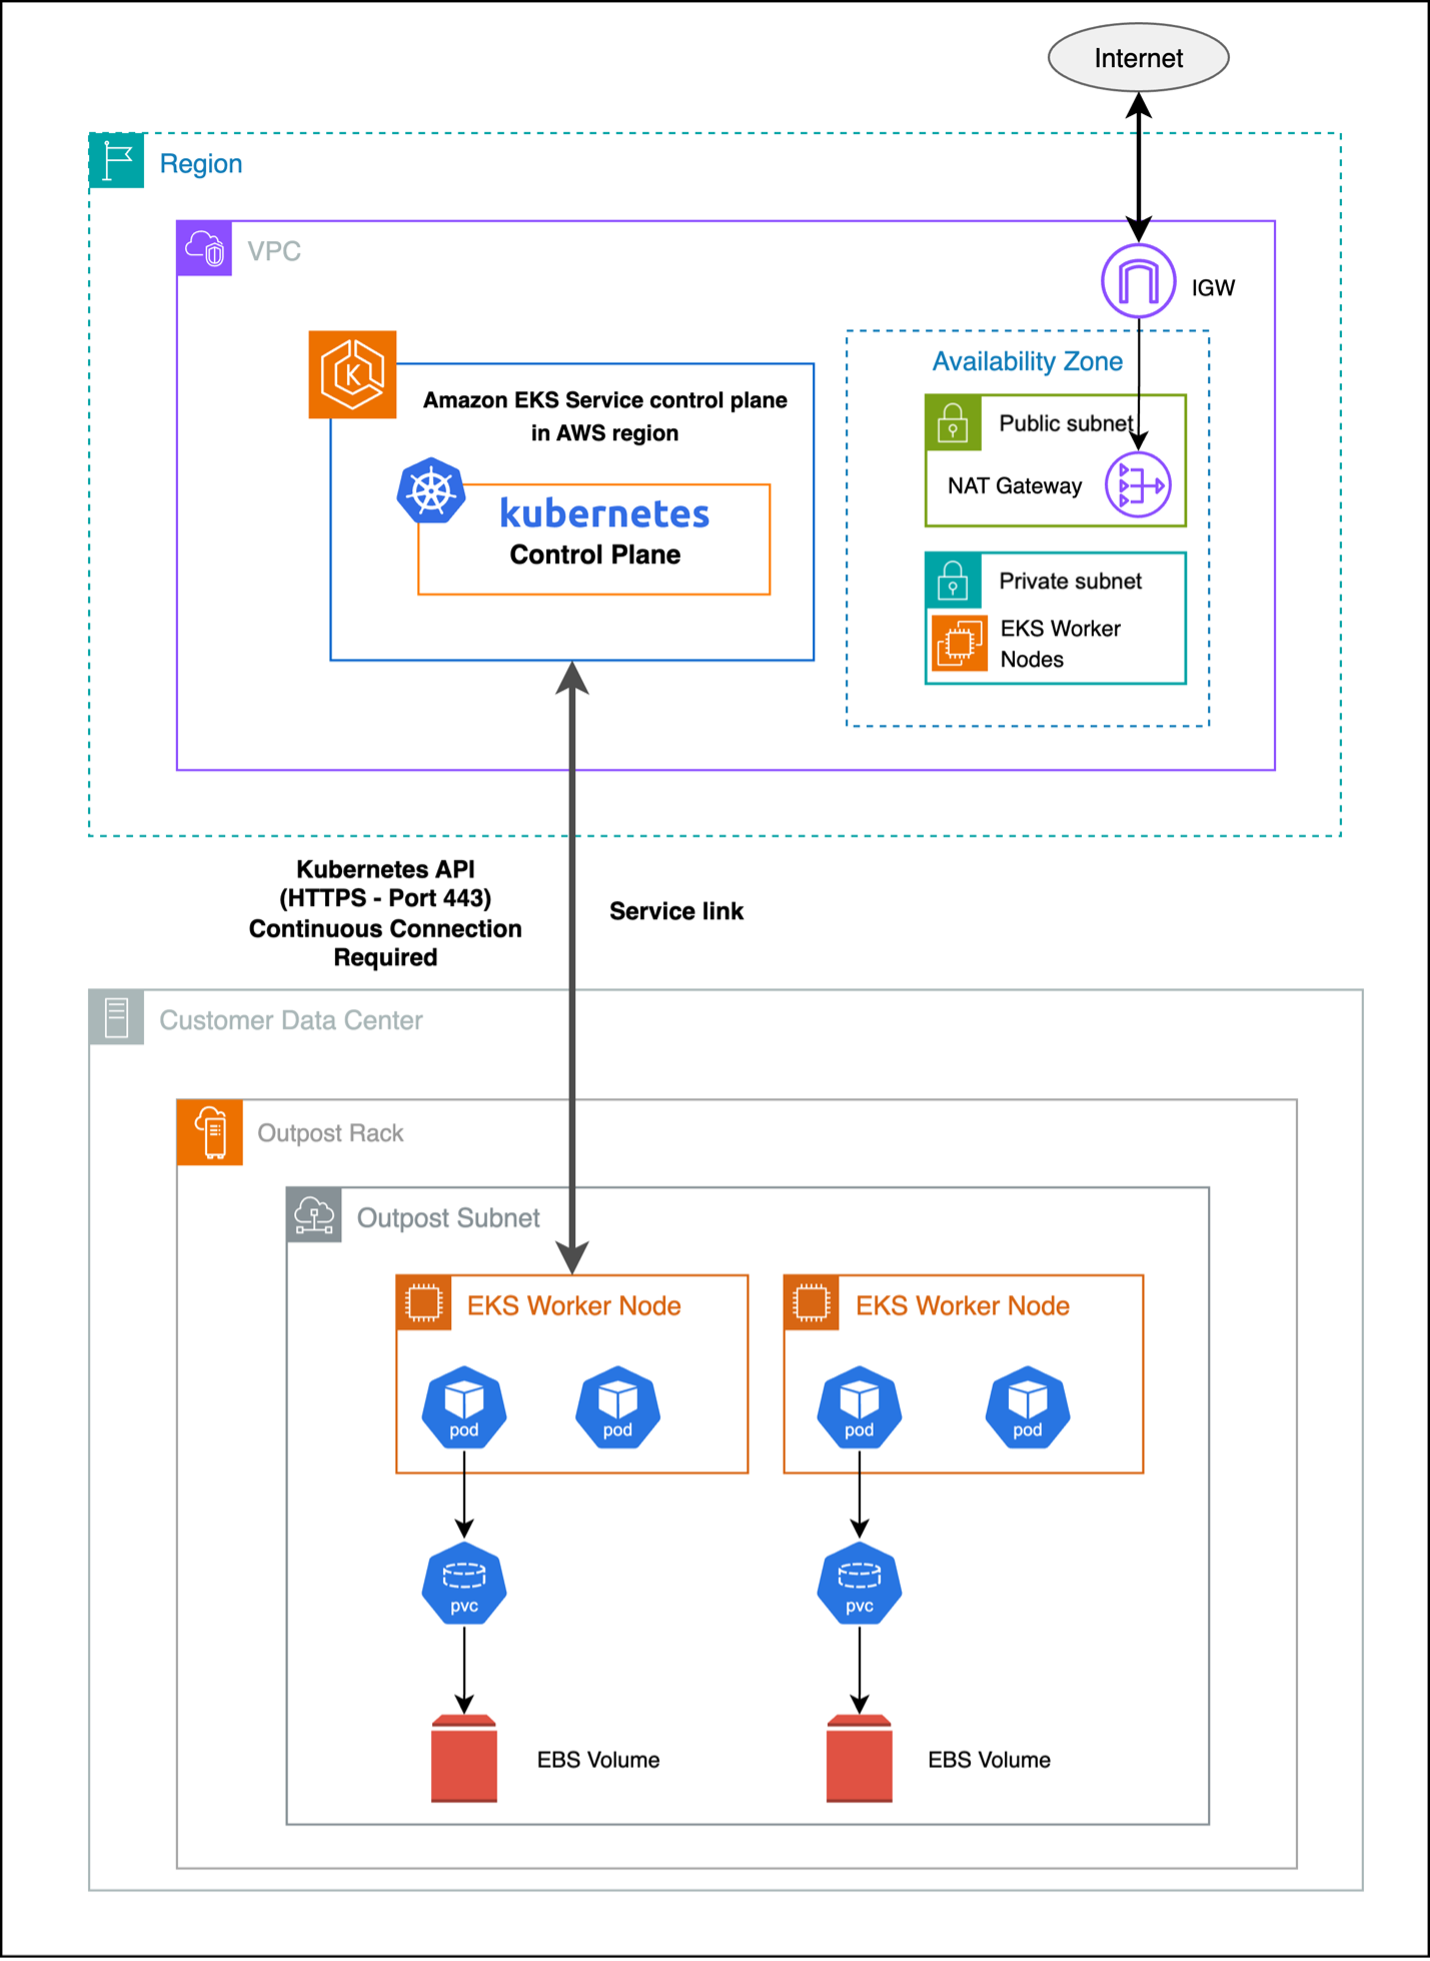
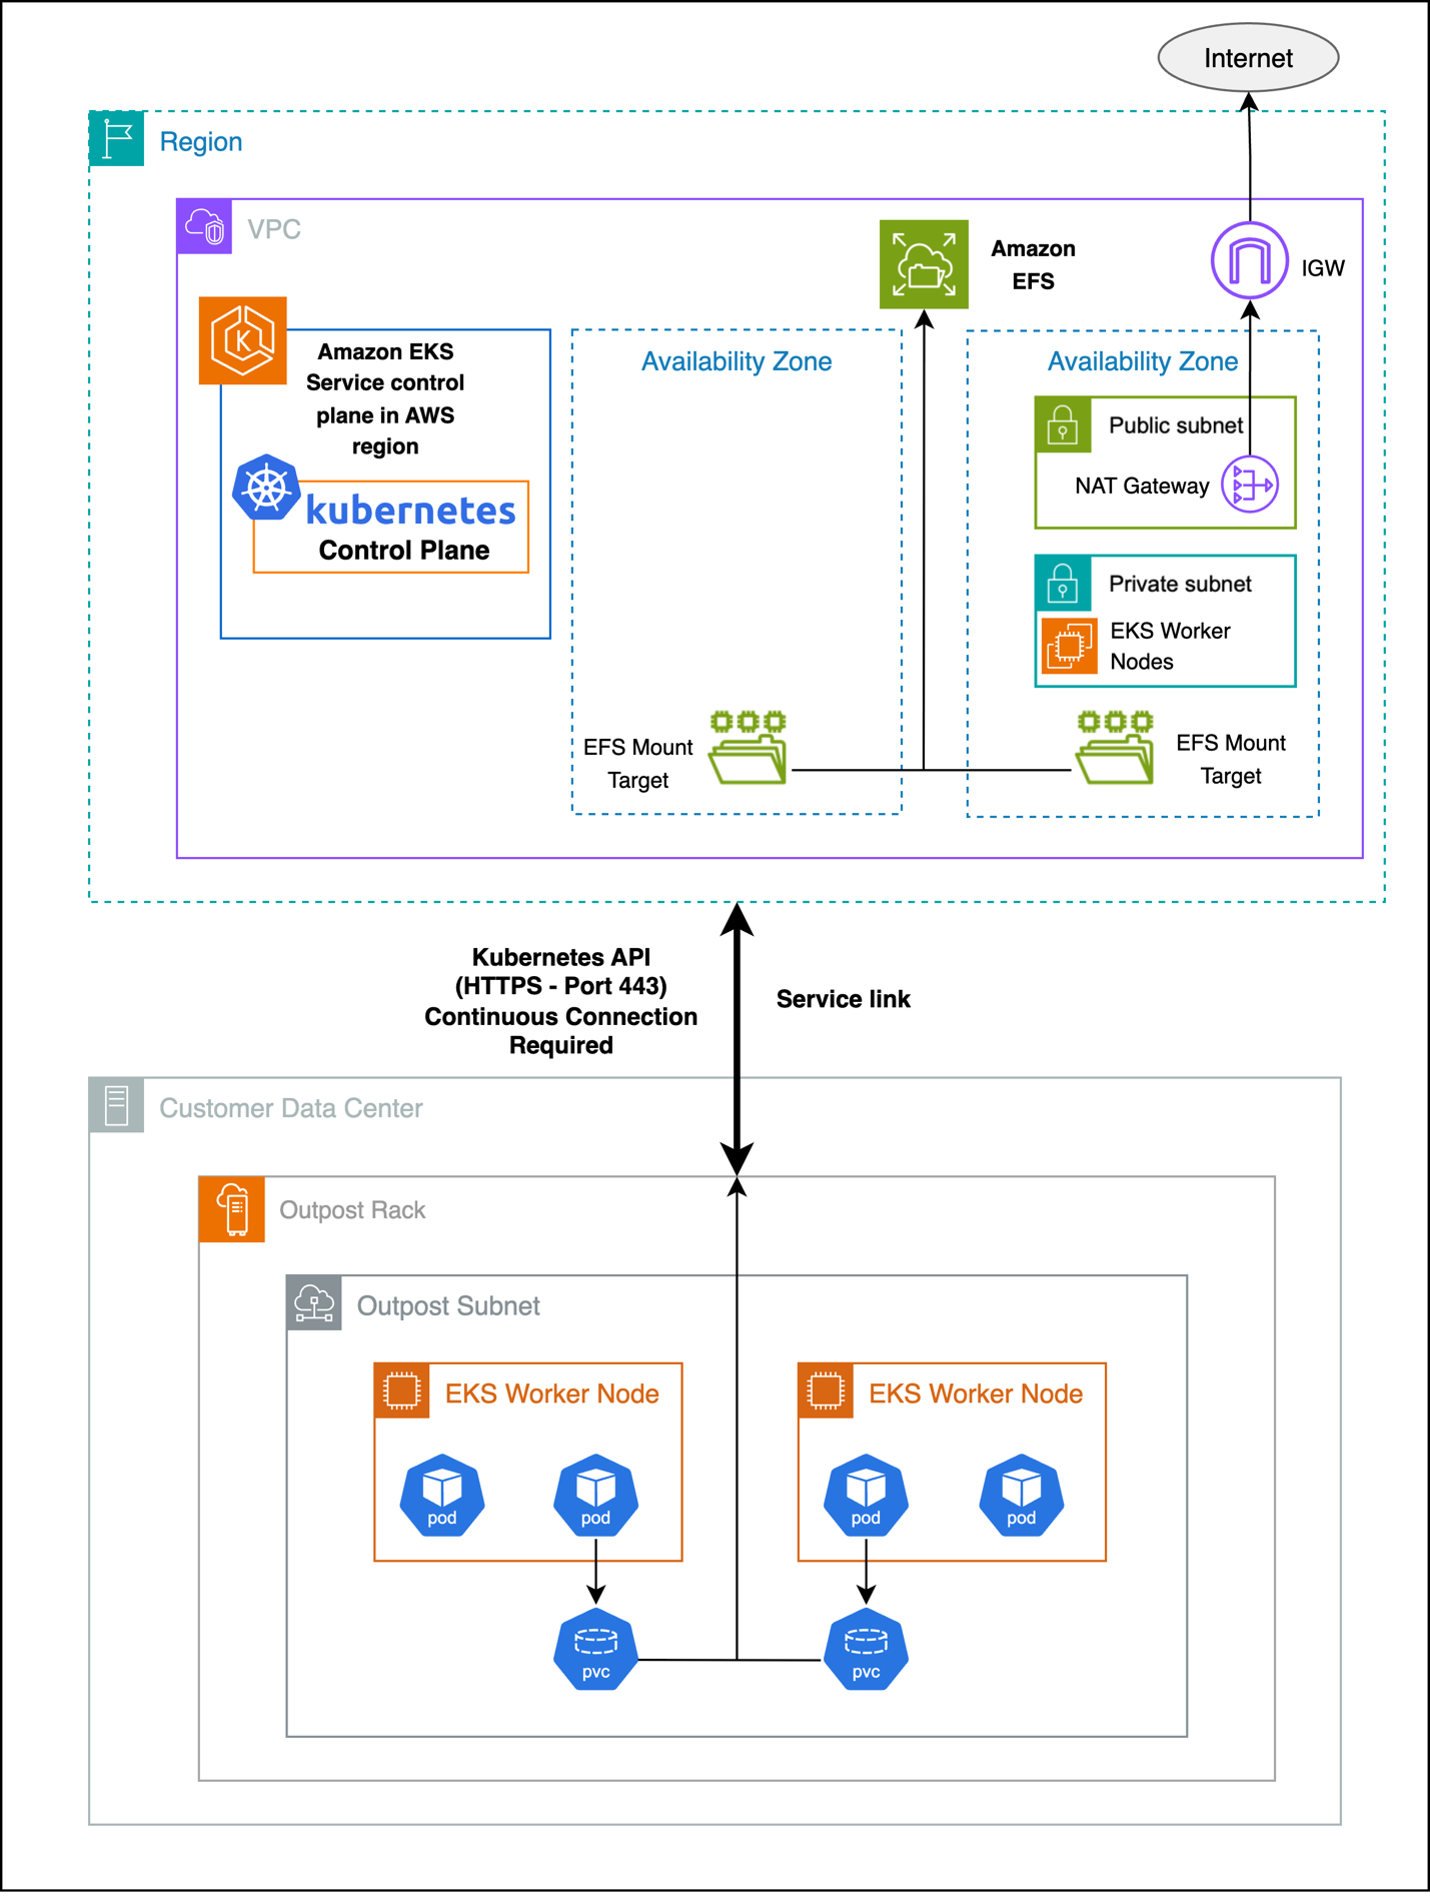
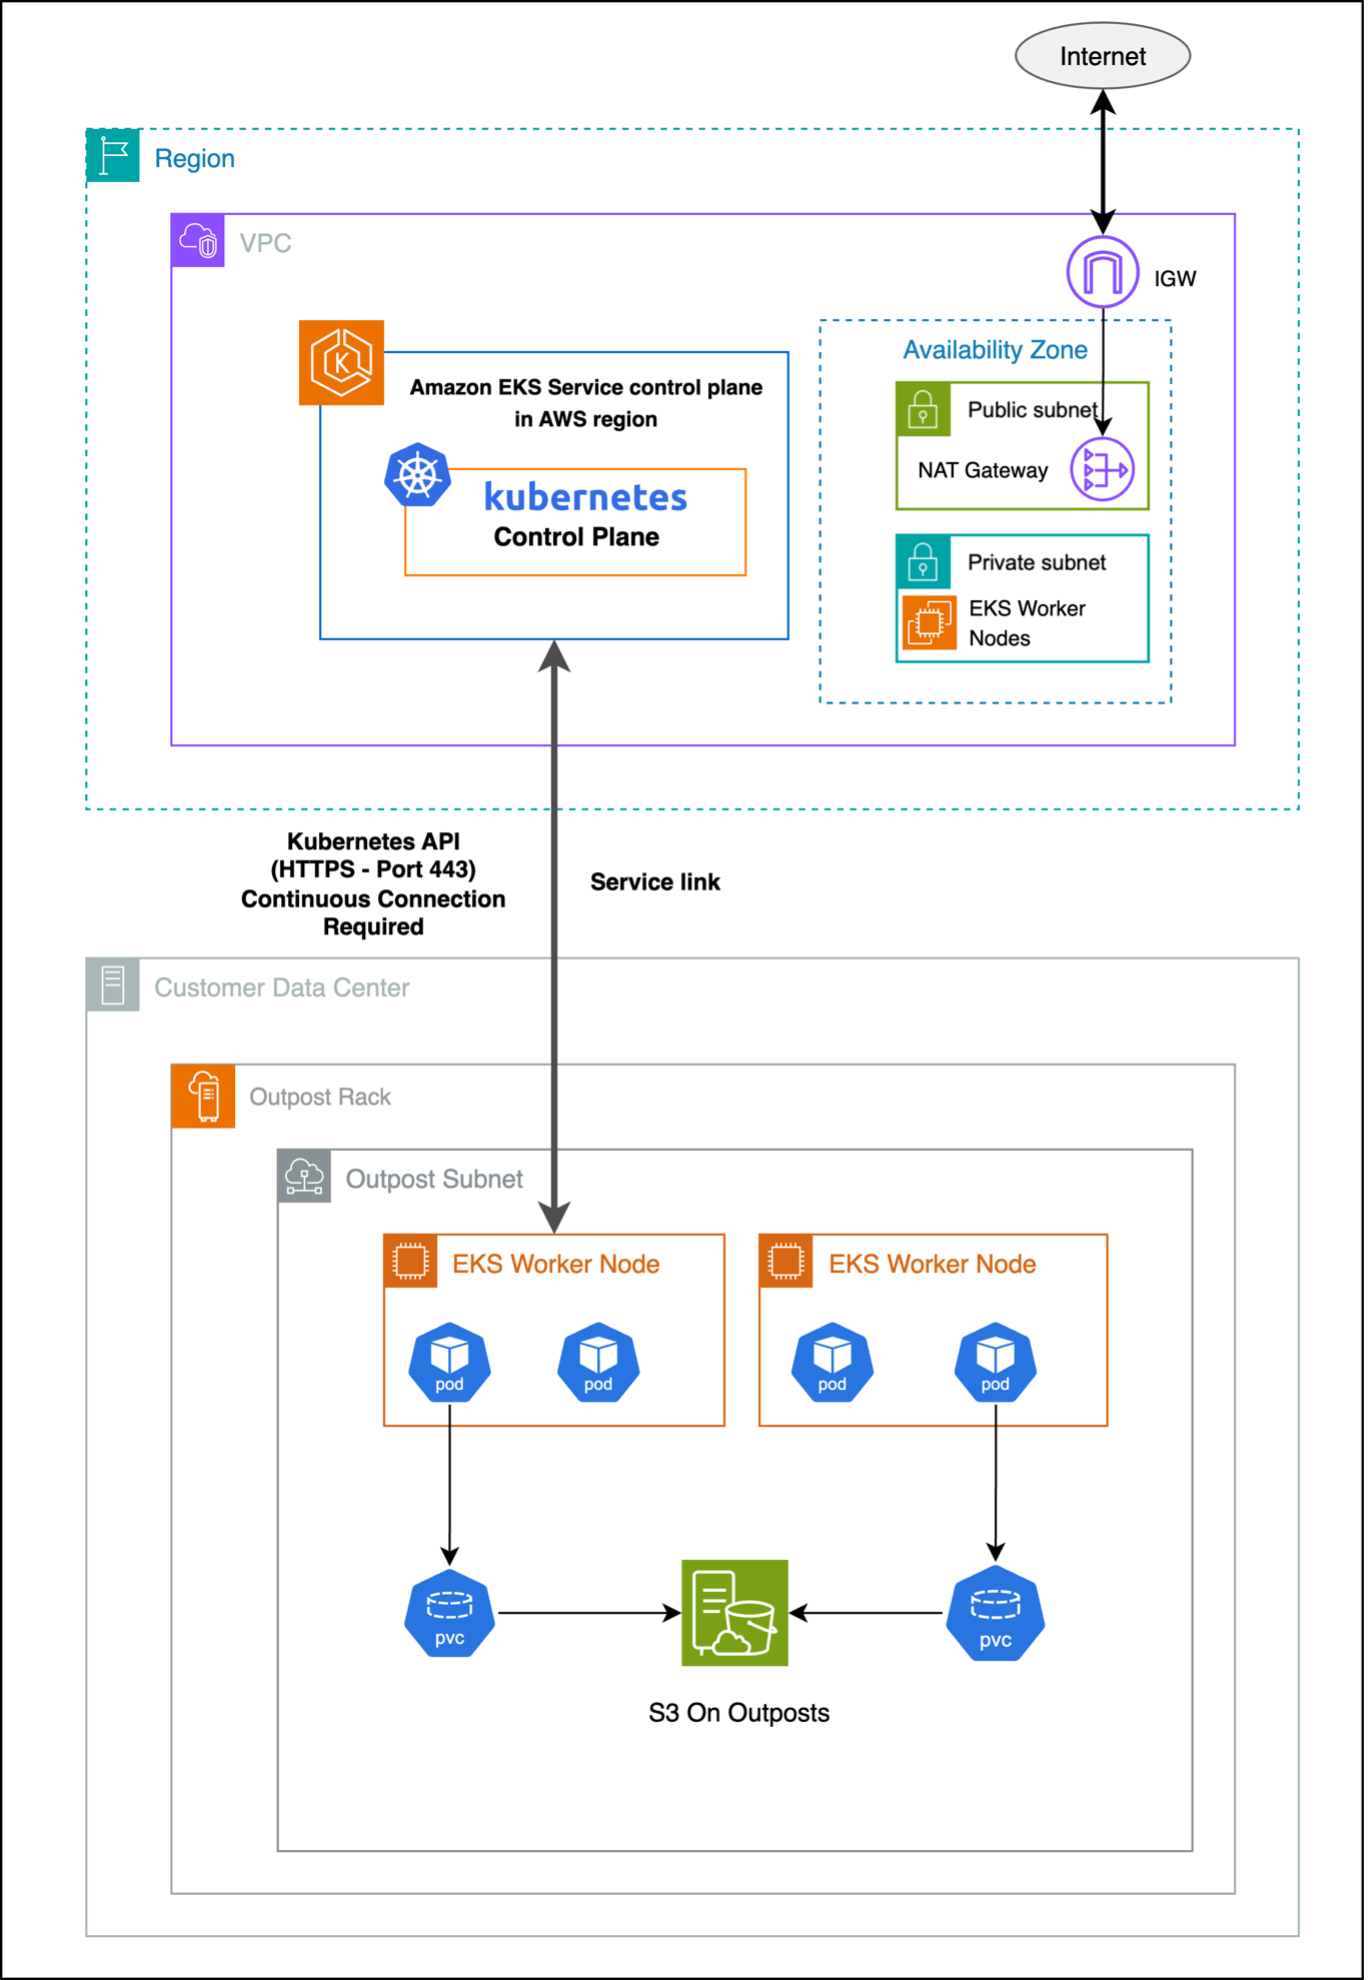
Amazon EKS extended clusters on Outposts provide a powerful solution for organizations seeking to use the benefits of Kubernetes while maintaining certain workloads on-premises, as shown in the following figure. This hybrid architecture allows businesses to extend their EKS clusters from the AWS Cloud to their own data centers or edge locations using Outposts. The Kubernetes control plane remains in the AWS Region, providing centralized management and benefiting from the AWS infrastructure in the cloud and on the Outpost.

Outposts is designed to be a connected service, and needs reliable network connectivity to the AWS Region using the Outposts service link.

Figure 1 : Extended cluster

Amazon EKS local cluster architecture

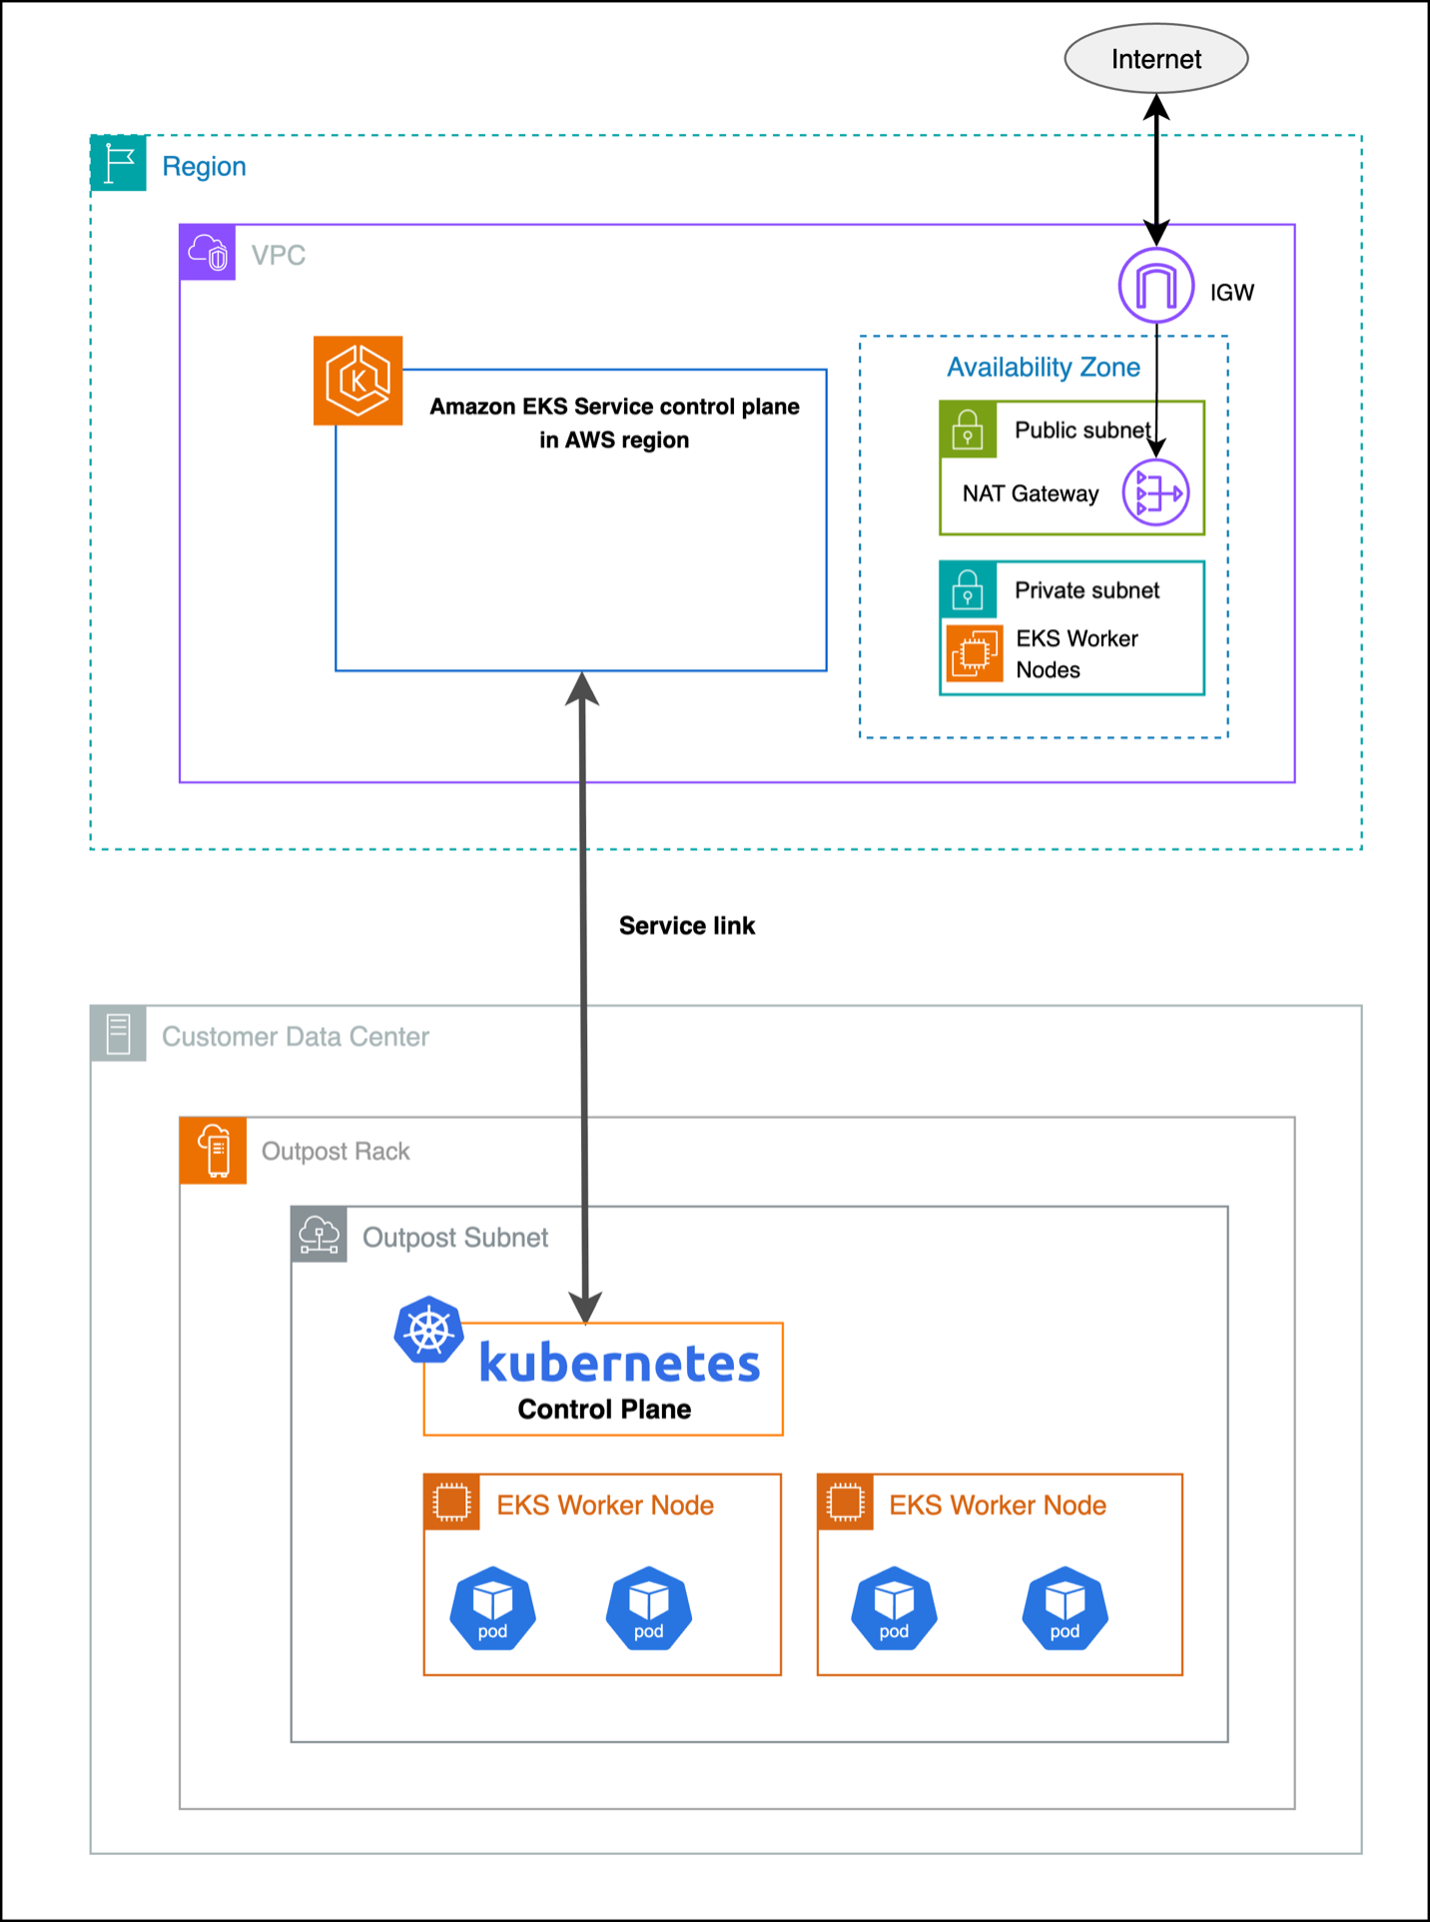
Amazon EKS local clusters deploy the Kubernetes control plane on your Outpost, as shown in the following figure. This provides greater network resilience against outages as cluster operations run entirely on the Outposts and reduces the dependency on network connectivity to the AWS Region. Having the Kubernetes control plane hosted on your Outpost also reduces latency for cluster operations.

  Figure 2: Local cluster

Storage options for Amazon EKS extended clusters on Outposts

Persistent Volumes (PV) and Persistent Volume Claims (PVC) serve as a critical abstraction layer in Kubernetes, separating the storage consumption details from storage provisioning, and allowing administrators to manage storage resources independently from how applications consume them. PVs and PVCs make sure of data persistence across pod restarts and rescheduling events, making them essential for applications that need to maintain state, such as databases, file storage systems, and other data-intensive workloads. The abstraction provided by PV and PVC enables platform-agnostic storage management, where applications can request storage through PVCs without needing to know the underlying storage implementation details. PVs and PVCs support dynamic provisioning through Storage Classes, allowing for automated storage allocation based on application demands, while also providing features such as access modes, capacity management, and reclaim policies to effectively manage the storage lifecycle in a Kubernetes cluster.

Integrating Amazon EBS with Amazon EKS

Amazon Elastic Block Store (Amazon EBS) provides high-performance block storage that’s ideal for low-latency applications providing consistent performance. When deployed on Outposts racks, EBS volumes are stored on the Outposts hardware, providing significant performance advantages over network-attached storage solutions, as shown in the following figure.

Figure 3 : Integrating Amazon EBS with Amazon EKS on Outposts

Benefits and use cases

  • Storage: EBS volumes on Outposts racks provide data access without dependency on external connectivity.
  • Performance: Local storage delivers consistent latency and high IOPS/throughput.
  • Cost: On-premises storage eliminates data transfer costs and reduces bandwidth needs, lowering the total cost of ownership.

Implementation considerations

Consider the following when using EBS on Outposts rack:

  • EBS volumes on Outposts are tied to a single rack and the availability zone the Outpost is homed to, needing applications to address single-point-of-failure risks.
  • Protect data using EBS snapshots in the parent Region and schedule regular backups.
  • Capacity on Outposts is finite, monitor Outposts storage usage and plan expansions proactively to avoid insufficient capacity errors.

Refer to Dynamic Volume Provisioning to learn more about deploying pod with the EBS volume attached.

Amazon EFS with Amazon EKS

Amazon Elastic File System (Amazon EFS) provides scalable, shared file storage that can be accessed across multiple AWS Availability Zones (AZs) and on-premises environments. Although Amazon EFS with Amazon EKS on Outposts maintains the same setup procedures as standard cloud deployments, there is a critical dependency on the service link connection between your Outposts and the AWS Region. Amazon EFS is not a locally supported service on Outposts, so connectivity to the AWS Region is required to use this service with your Outpost.

Amazon EFS allows multiple pods to concurrently access shared file systems. It is well-suited for applications that need collaborative data access, content management, and distributed processing workloads.

Amazon EFS as a persistent storage solution for Amazon EKS extended cluster instances

Amazon EFS as a PV for your Amazon EKS extended cluster operates through a hybrid architecture where the Amazon EFS file system resides in the Region, but mount points can be created on the worker nodes running on Outposts subnets through the service link as shown in the following figure.

Figure 4 : Amazon EFS as a persistent storage solution for extended clusters

Benefits and use cases

  • Shared storage capabilities: multiple pods can access a centralized file system, enabling shared data, code, and assets across instances.
  • Scalability: storage capacity and performance automatically scale with usage, eliminating manual provisioning and upfront planning.
  • Compliance: Amazon EFS provides full file system features and compatibility for traditional applications, such as locking, permissions, and directory structure.

Challenges and limitations

Consider the following when using Amazon EFS with Outposts:

  • Network latency: file access involves network traversal to Amazon EFS in the Region, adding more latency and making small or metadata operations potentially slow for latency-sensitive applications.
  • Throughput: aggregate throughput is restricted by the available bandwidth on the service link between the Outposts and AWS Region. This impacts concurrent access and large file transfers during peak usage.
  • Dependency on AWS Region connectivity: Amazon EFS needs continuous connectivity to the parent Region. Disruptions may affect file system availability, operations, and disaster recovery processes.
  • Data Transfer charges: Since EFS is in AWS Parent region and EKS worker nodes and pods are in Outpost additional charges are applicable.

You can refer to Amazon EFS Features and When to Choose Amazon EFS for more detailed insights into its capabilities and use cases.

Deploying pods on extended clusters using Amazon EFS as PV

Refer to Use Elastic File System Storage with Amazon EFS for deployment guidance. Note, Create Amazon EFS mount targets in subnets that are in the same Availability Zone (AZ) as the Outposts subnets.

Amazon S3 with Amazon EKS extended cluster

Amazon Simple Storage Service (Amazon S3) on Outposts delivers local object storage on your Outposts, allowing applications to use Amazon S3 APIs for storing and retrieving data while keeping it onsite. It is ideal for workloads that need Amazon S3 compatibility, low latency access to object data, and local data residency.

You should use Amazon S3 access point Amazon Resource Names (ARNs) and not bucket ARNs for proper integration with Amazon EKS workloads.

Learn more about Amazon S3 on Outposts.

Figure 5 : Amazon S3 with Amazon EKS extended cluster on Outposts

Benefits and use cases

  • Data archiving and compliance: Enables cost-effective, locally retained storage for logs, audit trails, regulatory compliance, backups, and sensitive healthcare data with strict residency requirements.
  • Content distribution and media: Provides ultra-low latency local storage for serving static content, media streaming, digital asset management, and gaming asset delivery.
  • Data lake and analytics: Supports local data processing for analytics, ETL, machine learning (ML), real-time Internet of Things (IoT) data handling, and business intelligence with reduced latency and transfer costs.
  • Application integration: Seamlessly integrates with Amazon S3 compatible apps for backup, synchronization, microservices storage, API-driven workflows, and container image management on-premises.

Refer to How is Amazon S3 on Outposts different from Amazon S3 and the Amazon S3 on Outposts documentation to learn more.

Deploying pods on extended clusters using Amazon S3 as PV

Step 1: Create Amazon S3 on Outposts bucket
Step 2: Create Amazon S3 Access Point (necessary for Amazon EKS integration)
Step 3: Configure IAM roles and policies
Step 4: Install Amazon S3 CSI driver
Step 5: Deploying your pod with Amazon S3 volume attached
Step 6: Complete Amazon S3 configuration with Kubernetes

Refer to the documentation Static Provisioning on Outposts bucket for more details on Step 5.

Best practices for optimizing performance

Optimizing performance starts with selecting the right storage type for your workload: Amazon EBS for low-latency, high-throughput block storage; Amazon EFS for shared POSIX-compliant file systems; and Amazon S3 for scalable object storage with API compatibility. Ensure proper volume sizing, monitor usage proactively, and configure CPU and memory requests accurately to balance performance and efficiency—auto scaling and QoS classes can further optimize resource management. Improve data locality by using local storage, apply caching with intelligent eviction, and design for efficient, asynchronous, and compressed data access patterns.

Monitoring and observability

Monitoring key performance metrics is essential to maintain storage efficiency and application reliability. For Amazon EBS, track IOPS, throughput, latency, burst balance, queue depth, and snapshot performance to avoid degradation—see the Amazon CloudWatch metrics for Amazon EBS for the full list. For Amazon EFS, monitor total I/O, throughput, client connections, metadata operations, burst credits, and Regional data transfers to support effective capacity planning—refer to CloudWatch metrics for Amazon EFS. For Amazon S3, observe request and error rates, data transfer, storage usage, latency, multipart upload efficiency, and access patterns to optimize performance and cost—see Metrics and dimensions.

Security considerations

Strong security practices are critical for Amazon EKS on Outposts. Use AWS Key Management Service (AWS KMS) for Amazon EBS encryption, encrypt Amazon EFS data at rest and in transit, and enable server- or client-side encryption for Amazon S3. Enforce TLS for all data transfers and apply key rotation with compliance controls. Implement least privilege IAM policies, scoped roles, and Kubernetes Role-Based Access Control (RBAC) for granular pod access. Secure traffic with security groups and NACLs, and maintain audit logs for all storage operations.

Cost optimization strategies

Manage storage costs by right-sizing volumes, automating lifecycle policies, selecting appropriate storage classes, monitoring data transfer, and using de-duplication and compression where applicable. Lower operational expenses through automated backups, infrastructure as code (IaC), monitoring automation, leveraging managed services, applying cost allocation tags, and conducting regular usage reviews.

Conclusion

Amazon EKS on Outposts empowers organizations to build hybrid applications with storage options that align to performance, compliance, and data residency needs. By selecting the right storage solution for each workload and leveraging Outposts’ local infrastructure, you can reduce latency, minimize network dependencies, and maintain consistency across environments. As Outposts capabilities continue to evolve, they offer a strong foundation for modern, resilient, and cost-efficient hybrid cloud architectures.

Reach out to your AWS account team, or fill out this form to learn more about running containarized applications on Outposts.

Streamline security response at scale with AWS Security Hub automation

Post Syndicated from Ahmed Adekunle original https://aws.amazon.com/blogs/security/streamline-security-response-at-scale-with-aws-security-hub-automation/

A new version of AWS Security Hub, is now generally available, introducing new ways for organizations to manage and respond to security findings. The enhanced Security Hub helps you improve your organization’s security posture and simplify cloud security operations by centralizing security management across your Amazon Web Services (AWS) environment. The new Security Hub transforms how organizations handle security findings through advanced automation capabilities with real-time risk analytics, automated correlation, and enriched context that you can use to prioritize critical issues and reduce response times. Automation also helps ensure consistent response procedures and helps you meet compliance requirements.

AWS Security Hub CSPM (cloud security posture management) is now an integral part of the detection engines for Security Hub. Security Hub provides centralized visibility across multiple AWS security services to give you a unified view of your cloud environment, including risk-based prioritization views, attack path visualization, and trend analytics that help you understand security patterns over time.

This is the third post in our series on the new Security Hub capabilities. In our first post, we discussed how Security Hub unifies findings across AWS services to streamline risk management. In the second post, we shared the steps to conduct a successful Security Hub proof of concept (PoC).

In this post, we explore how you can enhance your security operations using AWS Security Hub automation rules and response automation.

We walk through the setup and configuration of automation rules, share best practices for creating effective response workflows, and provide real-world examples of how these tools can be used to automate remediation, escalate high-severity findings, and support compliance requirements.

Security Hub automation enables automatic response to security findings to help ensure critical findings reach the right teams quickly, so that they can reduce manual effort and response time for common security incidents while maintaining consistent remediation processes.

Note: Automation rules evaluate new and updated findings that Security Hub generates or ingests after you create them, not historical findings. These automation capabilities help ensure critical findings reach the right teams quickly.

Why automation matters in cloud security

Organizations often operate across hundreds of AWS accounts, multiple AWS Regions, and diverse services—each producing findings that must be triaged, investigated, and acted upon. Without automation, security teams face high volumes of alerts, duplication of effort, and the risk of delayed responses to critical issues.

Manual processes can’t keep pace with cloud operations; automation helps solve this by changing your security operations in three ways. Automation filters and prioritizes findings based on your criteria, showing your team only relevant alerts. When issues are detected, automated responses trigger immediately—no manual intervention needed.

If you’re managing multiple AWS accounts, automation applies consistent policies and workflows across your environment through centralized management, shifting your security team from chasing alerts to proactively managing risk before issues escalate.

Designing routing strategies for security findings

With Security Hub configured, you’re ready to design a routing strategy for your findings and notifications. When designing your routing strategy, ask whether your existing Security Hub configuration meets your security requirements. Consider whether Security Hub automations can help you meet security framework requirements like NIST 800-53 and identify KPIs and metrics to measure whether your routing strategy works.

Security Hub automation rules and automated responses can help you meet the preceding requirements, however it’s important to understand how your compliance teams, incident responders, security operations personnel, and other security stakeholders operate on a day-to-day basis. For example, do teams use the AWS Management Console for AWS Security Hub regularly? Or do you need to send most findings downstream to an IT systems management (ITSM) tool (such as Jira or ServiceNow) or third-party security orchestration, automation, and response (SOAR) platforms for incident tracking, workflow management, and remediation?

Next, create and maintain an inventory of critical applications. This helps you adjust finding severity based on business context and your incident response playbooks.

Consider the scenario where Security Hub identifies a medium-severity vulnerability on an Elastic Compute Cloud instance. In isolation, this might not trigger immediate action. When you add business context—such as strategic objectives or business criticality—you might discover that this instance hosts a critical payment processing application, revealing the true risk. By implementing Security Hub automation rules with enriched context, this finding can be upgraded to critical severity and automatically routed to ServiceNow for immediate tracking. In addition, by using Security Hub automation with Amazon EventBridge, you can trigger an AWS Systems Manager Automation document to isolate the EC2 instance for security forensics work to then be carried out.

Because Security Hub offers OCSF format and schema, you can use the extensive schema elements that OCSF offers you to target findings for automation and help your organization meet security strategy requirements.

Example use cases

Security Hub automation supports many use cases. Talk with your teams to understand which fit your needs and security objectives. The following are some examples of how you can use security hub automation:

Automated finding remediation

Use automated finding remediation to automatically fix security issues as they’re detected.

Supporting patterns:

  • Direct remediation: Trigger AWS Lambda functions to fix misconfigurations
  • Resource tagging: Add tags to non-compliant resources for tracking
  • Configuration correction: Update resource configurations to match security policies
  • Permission adjustment: Modify AWS Identity and Access Management (IAM) policies to remove excessive permissions

Example:

  • IF finding.type = “Software and Configuration Checks/Industry and Regulatory Standards/CIS AWS Foundations Benchmark”
  • AND finding.title CONTAINS “S3 buckets should have server-side encryption enabled”
  • THEN invoke Lambda function “enable-s3-encryption”

Security finding workflow integration

Integrate findings into your workflow by routing them to the appropriate teams and systems.

Supporting patterns:

  • Ticket creation: Generate JIRA or ServiceNow tickets for manual review
  • Team assignment: Route findings to specific teams based on resource ownership
  • Severity-based routing: Direct critical findings to incident response, others to regular queues
  • Compliance tracking: Send compliance-related findings to GRC systems

Example:

  • IF finding.severity = “CRITICAL” AND finding.productName = “Amazon GuardDuty”
  • THEN send to SNS topic “security-incident-response-team”
  • ELSE IF finding.productFields.resourceOwner = “payments-team”
  • THEN send to SNS topic “payments-security-review”

Automated finding enrichment

Use finding enrichment to add context to findings to improve triage efficiency.

Supporting patterns:

  • Resource context addition: Add business context, owner information, and data classification
  • Historical analysis: Add information about previous similar findings
  • Risk scoring: Calculate custom risk scores based on asset value and threat context
  • Vulnerability correlation: Link findings to known Common Vulnerabilities and Exposures (CVEs) or threat intelligence

Example:

  • IF finding.type CONTAINS “Vulnerability/CVE”
  • THEN invoke Lambda function “enrich-with-threat-intelligence”

Custom security controls

Use custom security controls to meet organization-specific security requirements.

Supporting patterns:

  • Custom policy enforcement: Check for compliance with internal standards
  • Business-specific rules: Apply rules based on business unit or application type
  • Compensating controls: Implement alternatives when primary controls can’t be applied
  • Temporary exceptions: Handle approved deviations from security standards

Example:

  • IF finding.resourceType = “AWS::EC2::Instance” AND
    • finding.resourceTags.Environment = “Production” AND
    • finding.title CONTAINS “vulnerable software version”
  • THEN invoke Lambda function “enforce-patching-policy”

Compliance reporting and evidence collection

Streamline compliance documentation and evidence gathering.

Supporting patterns:

  • Evidence capture: Store compliance evidence in designated S3 buckets
  • Audit trail creation: Document remediation actions for auditors
  • Compliance dashboarding: Update compliance status metrics
  • Regulatory mapping: Tag findings with relevant compliance frameworks

Example:

  • IF finding.complianceStandards CONTAINS “PCI-DSS”
  • THEN invoke Lambda function “capture-pci-compliance-evidence”
  • AND send to SNS topic “compliance-team-notifications”

Set up Security Hub automation

In this section, you’ll walk through enabling up Security Hub and related services and creating automation rules.

Step 1: Enable Security Hub and integrated services

As the first step, follow the instructions in Enable Security Hub.

Note: Security Hub is powered by Amazon GuardDuty, Amazon Inspector, AWS Security Hub CSPM, and Amazon Macie, and these services also need to be enabled to get value from Security Hub.

Step 2: Create automation rules to update finding details and third-party integration

After Security Hub collects findings you can create automation rules to update and route the findings to the appropriate teams. The steps to create automation rules that update finding details or to a set up a third-party integration—such as Jira or ServiceNow—based on criteria you define can be found in Creating automation rules in Security Hub.

With automation rules, Security Hub evaluates findings against the defined rule and then makes the appropriate finding update or calls the APIs to send findings to Jira or ServiceNow. Security Hub sends a copy of every finding to Amazon EventBridge so that you can also implement your own automated response (if needed) for use cases outside of using Security Hub automation rules.

In addition to sending a copy of every finding to EventBridge, Security Hub classifies and enriches security findings according to business context, then delivers them to the appropriate downstream services (such as ITSM tools) for fast response.

Best practices

AWS Security Hub automation rules offer capabilities for automatically updating findings and integrating with other tools. When implementing automation rules, follow these best practices:

  • Centralized management: Only the Security Hub administrator account can create, edit, delete, and view automation rules. Ensure proper access control and management of this account.
  • Regional deployment: Automation rules can be created in one AWS Region and then applied across configured Regions. When using Region aggregation, you can only create rules in the home Region. If you create an automation rule in an aggregation Region, it will be applied in all included Regions. If you create an automation rule in a non-linked Region, it will be applied only in that Region. For more information, see Creating automation rules in Security Hub.
  • Define specific criteria: Clearly define the criteria that findings must match for the automation rule to apply. This can include finding attributes, severity levels, resource types, or member account IDs.
  • Understand rule order: Rule order matters when multiple rules apply to the same finding or finding field. Security Hub applies rules with a lower numerical value first. If multiple findings have the same RuleOrder, Security Hub applies a rule with an earlier value for the UpdatedAt field first (that is, the rule which was most recently edited applies last). For more information, see Updating the rule order in Security Hub.
  • Provide clear descriptions: Include a detailed rule description to provide context for responders and resource owners, explaining the rule’s purpose and expected actions.
  • Use automation for efficiency: Use automation rules to automatically update finding fields (such as severity and workflow status), suppress low-priority findings, or create tickets in third-party tools such as Jira or ServiceNow for findings matching specific attributes.
  • Consider EventBridge for external actions: While automation rules handle internal Security Hub finding updates, use EventBridge rules to trigger actions outside of Security Hub, such as invoking Lambda functions or sending notifications to Amazon Simple Notification Service (Amazon SNS) topics based on specific findings. Automation rules take effect before EventBridge rules are applied. For more information, see Automation rules in EventBridge.
  • Manage rule limits: This is a maximum limit of 100 automation rules per administrator account. Plan your rule creation strategically to stay within this limit.
  • Regularly review and refine: Periodically review automation rules, especially suppression rules, to ensure they remain relevant and effective, adjusting them as your security posture evolves.

Conclusion

You can use Security Hub automation to triage, route, and respond to findings faster through a unified cloud security solution with centralized management. In this post, you learned how to create automation rules that route findings to ticketing systems integrations and upgrade critical findings for immediate response. Through the intuitive and flexible approach to automation that Security Hub provides, your security teams can make confident, data-driven decisions about Security Hub findings that align with your organization’s overall security strategy.

With Security Hub automation features, you can centrally manage security across hundreds of accounts while your teams focus on critical issues that matter most to your business. By implementing the automation capabilities described in this post, you can streamline response times at scale, reduce manual effort, and improve your overall security posture through consistent, automated workflows.

If you have feedback about this post, submit comments in the Comments section. If you have questions about this post, start a new thread on AWS Security, Identity, and Compliance re:Post or contact AWS Support.
 

Ahmed Adekunle
Ahmed Adekunle

Ahmed is a Security Specialist Solutions Architect focused on detection and response services at AWS. Before AWS, his background was in business process management and AWS technology consulting, helping customers use cloud technology to transform their business. Outside of work, Ahmed enjoys playing soccer, supporting less privileged activities, traveling, and eating spicy food, specifically African cuisine.
Alex Wadell
Alex Wadell

Alex is a Senior Security Specialist Solutions Architect at AWS based in Scotland. Alex provides security architectural guidance and operational best practices to customers of all sizes, helping them implement AWS security services. When not working, Alex enjoys spending time sampling rum from around the world, walking his dogs in the local forest trails, and traveling.
Kyle Shields
Kyle Shields

Kyle is a WW Security Specialist Solutions Architect at AWS focused on threat detection and incident response. With over 10 years in cybersecurity and more than 20 years of Army service, he helps customers build effective incident response capabilities while implementing information and cyber security best practices.

Why “Build” Is a Bigger Distraction Than You Think for Neoclouds

Post Syndicated from Maddie Presland original https://www.backblaze.com/blog/why-build-is-a-bigger-distraction-than-you-think-for-neoclouds/

A decorative image showing different columns with a dollar sign indicator.

The rise of the neocloud and open cloud ecosystem are dethroning the major cloud providers. Companies like Vultr, Akamai, and CoreWeave are proving that developers don’t need a walled garden to build world-class applications. Instead, teams can build their own best-of-breed stacks and choose specialized providers that do just one thing exceptionally well, such as high-performance compute, AI inference, or databases.

But this new stack creates a critical decision point: What about storage?

For the neocloud model to work, data needs to be open and flexible. Consider the economics of the split-stack. If a neocloud lacks a robust storage layer, the customer often defaults to keeping their data with a major cloud company like AWS. This creates a financial trap where every time the neocloud application needs to process that data, it must retrieve it from the big three cloud providers’ walled gardens. The resulting egress fees can negate the cost savings of moving to a neocloud provider in the first place.

For a technical-first neocloud CTO, the default answer is almost reflexive. “We’ll build it. It’s just storage. How hard can it be?”

It’s a fair question, and it usually kicks off an internal engineering debate that sounds something like this:

  • Should we use Ceph on commodity hardware, or design our own purpose-built architecture?
  • Do we currently have the data center capacity to stand up multi-petabyte-scale storage clusters?
  • Can we repurpose our existing older generation hardware, or do we need to order all-new equipment?
  • Is commodity object storage really the best use of our precious rack space, or would offering this service require an expensive data center expansion?

These are the right questions. But the answers often lead to a trap.

The build trap: When storage becomes the wrong problem

Whether you choose the software route (Ceph) or the hardware route (purpose-built), you aren’t just adding a new service feature. Both paths risk distracting your best engineers from your core business by forcing them to master a new (and expensive) specialty: storage infrastructure.

This guide reveals the true costs of both “build” paths, and why the smartest move for a neocloud might be to not build at all.

Path 1: The Ceph approach

On paper, Ceph is the obvious choice. It’s open-source and scalable. It unifies object, block, and file storage. And it runs on commodity hardware.

But people and complexity make Ceph more expensive than you’d think. 

First of all, Ceph is not “set it and forget it.” It is notoriously complex to deploy, manage, and tune at petabyte scale. That means you can’t just assign Ceph to a junior sysadmin. You’ll have to hire and retain a dedicated team of expensive, hard-to-find Ceph specialists. 

This creates a massive resource drain. Instead of allocating your engineering headcount to build your next great compute plan or AI feature, you’re burning the budget on operational overhead. And that overhead is significant because getting real-world performance out of Ceph depends on a deep, constant tuning of CRUSH maps, OSDs, and the perfect (and constantly evolving) co-design of the underlying hardware.

Ultimately, Ceph isn’t just a software choice; it’s a strategic commitment to building a storage operations division that works in tandem with all your other ops and engineering teams.

Path 2: The “purpose-built” approach

This approach gives you a lot of control. You can design hardware specifically for your cost model, data center layout, and performance needs.

But it comes with a catch: it means becoming a hardware R&D company.

Trust us, we know. It’s the path we took over 15 years ago. It worked for us, but looking back, it only made sense for two reasons:

  1. The era. The operational realities of cloud storage were different back in 2007 when we launched the company. We simply didn’t have the options—and therefore, the competition around pricing and features—that we have now.
  1. The pivot. We very quickly shifted our focus from being a single-product, consumer-focused company to a cloud storage provider whose first customer was Backblaze Computer Backup. We chose to double down on the infrastructure investment we’d made to support that scale.

The reality of the R&D treadmill

Our original Storage Pod, which we open sourced in the Petabytes on a Budget blog, required deep R&D to design a custom chassis, source specific components, and solve physics problems such as mass drive vibration and power draw.

However, solving those physics problems once was just the beginning. To stay competitive, we had to keep innovating. In fact, we’ve gone through seven major versions of our Storage Pods (1.0, 2.0, 3.0, 4.0, 4.5, 5.0, 6.0). After all that R&D, we eventually found that the build/buy incentives had flipped and commodification had finally caught up. 

But to even make the decision to stop building custom chassis, we had to perform the same kind of testing we did for every previous version. Each iteration required new engineering to solve for higher drive densities, extended chassis lengths, changing cooling needs, and updated networking.

The operational reality

You’re not just “one and done” on drives or servers. Data centers are in constant flux. You are continually replacing old drives with new ones in existing chassis. Each time a new drive model enters the fleet, it must go through extensive testing to ensure it improves (or at least maintains) operations within the data center environment.

And drives are just one part of the equation. You also have to get files into and out of the data center efficiently. This requires constant, forward-thinking improvements in areas such as:

In other words, choosing the purpose-built path is a strategic commitment to becoming a full-time hardware and software engineering, supply chain, cybersecurity, and logistics company. If that sounds exhausting, that’s because it is.

Choose your distraction

The ultimate choice you need to make isn’t Ceph vs. purpose-built. The choice is, which resource-draining specialty do you want your product, engineering, and ops teams to be distracted by?

Do you want your best (and most expensive) engineers spending their days troubleshooting esoteric Ceph tuning parameters? Or would you rather have them re-designing a server chassis to introduce new CPU and GPU hardware and figuring out how to add essential security features with minimal overhead?

The answer is neither.

You want them focused on your specialty—building a better compute service, a faster AI model, or a more resilient database. Every hour they spend fighting with storage infrastructure is an hour they aren’t spending on the product your customers actually pay for.

The ideal solution: Storage as a specialty partner

This is why we exist. 

Backblaze was built on the fundamental belief that storage is a specialty. We’ve spent 15+ years solving these hardware and operational problems so that you don’t have to.

A symbiotic relationship

The neocloud ecosystem thrives on interoperability. It functions best not when every provider tries to build the full stack, but when they connect with independent, open, and easy-to-use layers.

When neoclouds partner with Backblaze, the dynamic shifts from building to enabling. You gain a petabyte-scale storage layer that is:

  • Instantly available. No lead times, no hardware sourcing, no build-out.
  • S3 compatible. It fits seamlessly into your existing tools and your customers’ workflows.
  • Zero overhead. None of the R&D distraction and operational weight we outlined above.

We provide the foundational storage that enables the entire open cloud ecosystem to compete on equal footing against the “Big Three” cloud providers.

Focus on what makes your neocloud great. Let Backblaze handle the storage. Learn more about Powered by Backblaze, or reach out to our storage experts to start a conversation. 

The post Why “Build” Is a Bigger Distraction Than You Think for Neoclouds appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Firefox 147 released

Post Syndicated from jzb original https://lwn.net/Articles/1053995/

Version
147.0
of the Firefox web browser has been released. Notable
changes in this release include support for the XDG Base
Directory specification
, enabling local
network access restrictions
for users with enhanced
tracking protection
(ETP) set to “Strict”, and a fix that improves
Firefox’s rendering with GNOME on fractionally scaled
displays. Firefox 147 also includes a number of security
fixes
, including several sandbox-escape vulnerabilities.

Security updates for Tuesday

Post Syndicated from jzb original https://lwn.net/Articles/1053988/

Security updates have been issued by AlmaLinux (mariadb10.11, mariadb:10.11, mariadb:10.3, mariadb:10.5, and tar), Debian (net-snmp), Fedora (coturn, NetworkManager-l2tp, openssh, and tuxanci), Mageia (libtasn1), Oracle (buildah, cups, httpd, kernel, libpq, libsoup, libsoup3, mariadb:10.11, mariadb:10.3, openssl, and podman), SUSE (cpp-httplib, ImageMagick, libtasn1, python-cbor2, util-linux, valkey, and wget2), and Ubuntu (google-guest-agent, linux-iot, and python-urllib3).

Learning from Code Clubs around the world: How approaches differ but values are shared

Post Syndicated from Sarah Lygoe original https://www.raspberrypi.org/blog/learning-from-code-clubs-around-the-world-how-approaches-differ-but-values-are-shared/

Every week, young people around the world gather in libraries, classrooms, community centres, and makerspaces to create with code. From Gujarat to Glasgow, Nairobi to New Jersey, the settings may differ, but the energy is unmistakable. 

Code Club meeting at the shared hub at AEF Reuben in Kenya

We set out to learn from the wealth of experiences within the global Code Club community: how clubs adapt to local needs, and which practices consistently support young people’s learning. Although we found small differences in how clubs make Code Club work locally, what stands out far more are the shared principles that make it work everywhere. Here we share stories from across our network that collectively paint a vibrant picture of what makes this movement work.

Inspiration from the people who make Code Club thrive

One theme runs through every story: Code Club is powered by people who really understand the needs of their community.

During a visit to a set of Code Clubs in India, our team met a group of girls who once faced barriers to attending school. Now, they are confidently creating Scratch projects and exploring new technologies. Their club leader explained how a simple change — allowing girls to attend school wearing traditional attire — opened doors for families. Seeing these young creators code with pride is a vivid reminder of how opportunity can reshape futures.

Welspun Vapi Code Club in Gujarat

A club leader at Better Juniors Digital Club at Better Life Primary and Junior School in Kenya described how their programme began with just one laptop. Rather than letting that limit what learners could do, he found solutions everywhere: applying for grants, borrowing digital space from a nearby hub, and setting up equipment so children could work on projects together. His determination effectively created a bridge between schools and resources, opening up real opportunities for every child to learn.

We also heard from educators whose clubs have become long-standing pillars of their communities. At Rhiwbina Library in Wales, leaders have been running Code Club for over a decade, creating a space where older creators naturally guide new ones. When asked about club rules, one child replied: “There’s only one and that’s ‘respect’.” That simple principle continues to shape a joyful, collaborative atmosphere.

Fiona Lindsay and pupils at Hillside Primary School in Scotland

And sometimes the inspiration comes from the young people themselves. At Hillside Primary in Scotland, an enthusiastic creator took it upon himself to run taster sessions and codealongs for new members, helping them discover whether Code Club was right for them. His enthusiasm and leadership were infectious, and that spirit of young people lifting up their peers is something we’ve seen in clubs all over the world.

Moments of joyful learning capture the spirit of Code Club

In one club that meets across three different venues in Pennsylvania, USA — a creative arts centre, a coffee shop, and a library — the excitement became contagious. The librarian, Miss Sandy, was so inspired by the learners’ projects — including the moment they added “Shredder Cat”, the library’s pet mascot, into their digital creations — that she has begun learning to code alongside them.

Miss Sandy, Ruth, and her Code Club in Pennsylvania
Miss Sandy, Ruth, and her Code Club in Pennsylvania 

At one showcase event in India, learners proudly demonstrated text-to-speech and video-sensing projects — remarkable achievements for many of them in their first year of coding. They explained their ideas with confidence and clarity, sharing the logic behind their work as parents, teachers, and mentors looked on with pride. 

In the UK, we experienced a beautiful moment at Fakenham Academy where the room filled with a chorus of squarks, clicking, tapping, and squeaking sounds as learners adapted the Grow a Dragonfly project in their own creative ways.

From applause erupting whenever a project is finished to a room buzzing with micro:bits or young people debugging together on a shared laptop, these snapshots show Code Club at its best.

All about community: Belonging, identity, and a resourceful spirit

Whatever the context or setting, Code Club leaders are resourceful. They are not waiting for others to solve their challenges; together with their creators, they are finding local solutions that work. Communities share equipment, mentor each other, offer space, and build continuity for learners in imaginative ways. Young people are gaining far more than digital skills: they are developing belonging, confidence, and a clear sense that they are part of something bigger.

For example, in a club in Kenya, two groups learnt side by side in a shared space. Younger learners were welcomed by older peers who acted as mentors, creating a real sense of community — collaborative, vibrant, and full of pride in each other’s achievements.

Learners in a Code Club in Kenya.

We also saw how deeply this work is woven into people’s identities. One team member visiting three clubs in Malvern, UK, wrote about Bob Bilsland, a Code Club champion for 13 years, describing how naturally he connected with learners at their own level and how fully he embodied the role of mentor and champion:

“Seeing his versatility as he mentored, sparked excitement and connected with creators at their own level was a thing to behold… he truly walks the talk.”

The impact can sometimes show up in unexpected ways. Holly, a leader from Illinois, USA, shared that her learners wear their Code Club t-shirts to school as “spirit gear” on Fridays. She told us how much this meant to her students:

“They absolutely love their shirts and are thrilled to be able to wear them… It makes them feel like a team.” A reminder that belonging matters just as much as skills.

Across every example, we saw resilience, creativity, and generosity in action because Code Clubs grow from strong communities.

Locally rooted but globally informed

These stories underscore something essential: Code Club grows not because of any one model, but because communities everywhere make it their own. Sandra Keeru, Programme Coordinator in Kenya, put it beautifully when she reflected that:

“Code Club is locally rooted but globally informed.” 

Each club reflects the needs, culture, and creativity of its community, yet everywhere the same shared values shine through: curiosity, inclusion, and the belief that young people can achieve remarkable things.

Code Club is more than just learning to code; it’s about creating opportunities, encouraging confidence, and building a global network of digital creators. Whether you’re a mentor, educator, or young digital maker, there’s a place for you in the community. Start your Code Club journey today and join a global community of digital creators.

The post Learning from Code Clubs around the world: How approaches differ but values are shared appeared first on Raspberry Pi Foundation.

The collective thoughts of the interwebz