Beyond IAM access keys: Modern authentication approaches for AWS

Post Syndicated from Mitch Beaumont original https://aws.amazon.com/blogs/security/beyond-iam-access-keys-modern-authentication-approaches-for-aws/

When it comes to AWS authentication, relying on long-term credentials, such as AWS Identity and Access Management (IAM) access keys, introduces unnecessary risks; including potential credential exposure, unauthorized sharing, or theft. In this post, I present five common use cases where AWS customers traditionally use IAM access keys and present more secure alternatives that you should consider.

AWS CLI access: Embrace CloudShell

If you’re primarily using access keys for AWS Command Line Interface (AWS CLI) access, consider AWS CloudShell—a browser-based CLI that minimizes the need for local credential management while providing the same powerful CLI capabilities that you’re accustomed to.

AWS CLI with enhanced security: IAM Identity Center

If you need a more robust solution, AWS CLI v2 combined with AWS IAM Identity Center offers a superior authentication approach. This integration enables:

  • Centralized user management
  • Seamless multi-factor authentication (MFA) integration
  • Enhanced security controls

Configuration is straightforward using the AWS CLI documentation, and MFA can be enabled following the IAM Identity Center MFA guide.

Local development: IDE integration

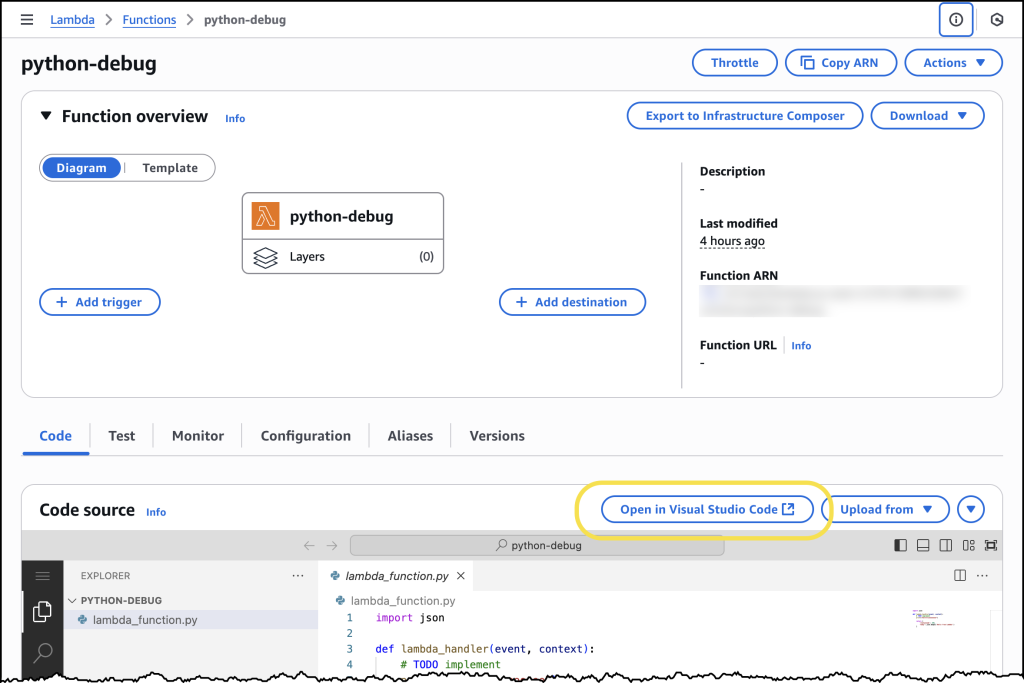
For developers working in local environments, modern integrated development environments (IDEs) such as Visual Studio Code, with AWS Toolkit support offer secure authentication through IAM Identity Center. This alleviates the need for static access keys while maintaining a smooth development experience. Learn more about AWS IDE integrations.

AWS compute services and CI/CD access

When your applications and automation pipelines need AWS resource access, whether running on AWS compute services (Amazon Elastic Compute Cloud (Amazon EC2), Amazon Elastic Container Service (Amazon ECS), or AWS Lambda) or through continuous integration and delivery (CI/CD) tools, IAM roles can provide the ideal solution. These roles automatically manage temporary credential rotation and follow security best practices.

  • For AWS compute services: Use standard IAM roles with your compute resources. Review the EC2 IAM roles documentation for implementation details.
  • For AWS-hosted CI/CD: When using AWS CodePipeline or AWS CodeBuild for example, use service-linked roles to manage permissions securely.
  • For CI/CD tools self-hosted on Amazon EC2: If you’re running tools such as Jenkins or GitLab on AWS resources, use the instance profile roles the same as you would with other compute services.

For third-party CI/CD services (such as GitHub Actions, CircleCI, and so on), see External access requirements.

External access requirements

For scenarios involving third-party applications or on-premises workloads, AWS offers three methods:

  • Third-party applications: Implement temporary security credentials through IAM roles instead of static access keys. Never use root account access keys. See third-party access documentation.
  • On-premises workloads: Use AWS IAM Roles Anywhere to generate temporary credentials for non-AWS workloads. For more information, see Access for non AWS workloads.
  • CI/CD software as a service (SaaS): For cloud-based CI/CD services, use OpenID Connect (OIDC) integration with IAM roles to minimize the need for long-term credentials. This allows your CI/CD pipelines to obtain temporary credentials through trust relationships. See the AWS OIDC provider documentation for implementation details.

Best practice: Principle of least privilege

Regardless of your authentication method, always implement the principle of least privilege. This helps make sure that users and applications have only the permissions they need. For guidance on crafting precise IAM policies, see Techniques for writing least privilege IAM policies.

Note: AWS also offers policy generation based on AWS CloudTrail logs, helping you create permission templates based on actual usage patterns. Learn about this feature in the IAM policy generation documentation.

Conclusion

As you’ve seen, there are numerous secure alternatives to IAM access keys that you can use to enhance your AWS authentication strategy while reducing security risks. By using tools such as CloudShell, IAM Identity Center, IDE integrations, IAM roles, and IAM Roles Anywhere, you can implement robust authentication mechanisms that align with modern security best practices.Key takeaways:

  • Prefer temporary credentials over long-term access keys
  • Choose the authentication method that best fits your use case
  • Implement the principle of least privilege across all access methods
  • Take advantage of the built-in tools provided by AWS for policy generation and management
  • Regularly review and update your authentication methods as new solutions become available

By making these changes, you can not only improve your security posture but also streamline your authentication processes across your AWS environment. Start small by identifying your current IAM access key use cases and gradually transition to these more secure alternatives. Your future self—and your security team—will thank you.

If you have feedback about this post, submit comments in the Comments section below.

Mitch Beaumont

Mitch Beaumont

Mitch is a Principal Solutions Architect for Amazon Web Services based in Sydney, Australia. Mitch works with some of Australia’s largest financial services customers, helping them to continually raise the security bar for the products and features that they build and ship. Outside of work, Mitch enjoys spending time with his family, photography, and surfing.

Building resilient multi-tenant systems with Amazon SQS fair queues

Post Syndicated from Maximilian Schellhorn original https://aws.amazon.com/blogs/compute/building-resilient-multi-tenant-systems-with-amazon-sqs-fair-queues/

Today, AWS introduced Amazon Simple Queue Service (Amazon SQS) fair queues, a new feature that mitigates noisy neighbor impact in multi-tenant systems. With fair queues, your applications become more resilient and easier to operate, reducing operational overhead while improving quality of service for your customers.

In distributed architectures, message queues have become the backbone of resilient system design. They act as buffers between components, allowing services to process work asynchronously and at their own pace. When a sudden traffic spike hits your application, queues prevent cascading failures by buffering work and ensuring that downstream services aren’t overwhelmed. Amazon SQS has long been a go-to solution for developers building scalable applications because it’s a fully managed serverless solution that can seamlessly scale to ingest millions of messages per second.

In this post, you learn how to use Amazon SQS fair queues and understand their inner workings through a practical example.

Overview

Many modern applications follow a multi-tenant architecture, where a single application instance serves multiple tenants. A tenant is any entity that shares resources with others. It could be a customer, client application, or request type. This approach reduces operational costs and simplifies maintenance through efficient resource utilization. One example of such shared resources are queues and their associated consumer capacity.

However, multi-tenant systems face challenges when one tenant becomes a noisy neighbor. This tenant impacts others by overutilizing your system’s resources. With queues, this tenant causes a backlog by sending a large volume of messages or by requiring longer processing time. Regular queues deliver older messages first, which increases message dwell time for all tenants in such scenarios. This makes it difficult to maintain quality of service and forces teams to over-provision resources or build complex custom solutions.

Amazon SQS fair queues help maintain low dwell time for other tenants when there is a noisy neighbor. This happens transparently without requiring changes to your existing message processing logic. You define what constitutes a tenant in your system, and Amazon SQS handles the complex orchestration of mitigating noisy neighbor impact.

How it works

Amazon SQS continually monitors the distribution of messages received but not yet deleted (in-flight) by consumers across all tenants. When the system detects an imbalance:

  1. It identifies the noisy tenant, the one causing the queue to build a backlog.
  2. It automatically adjusts message delivery order to prioritize messages belonging to quiet (non-noisy) tenants.
  3. It maintains overall queue throughput.

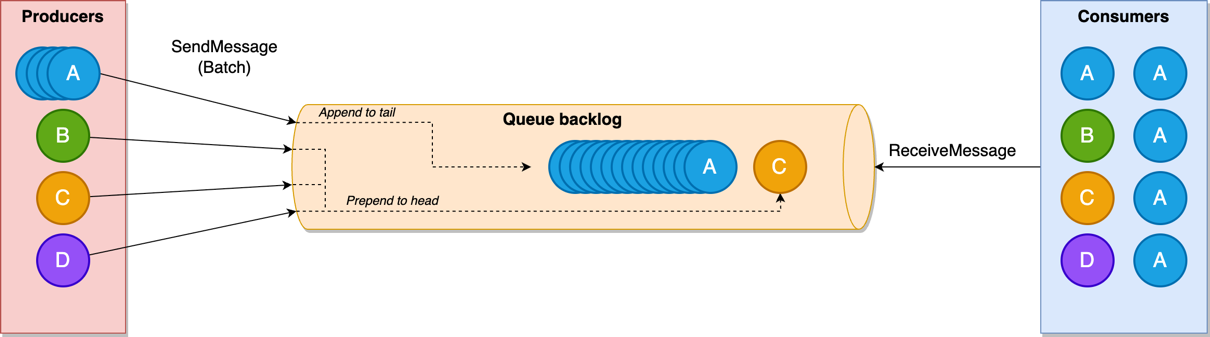
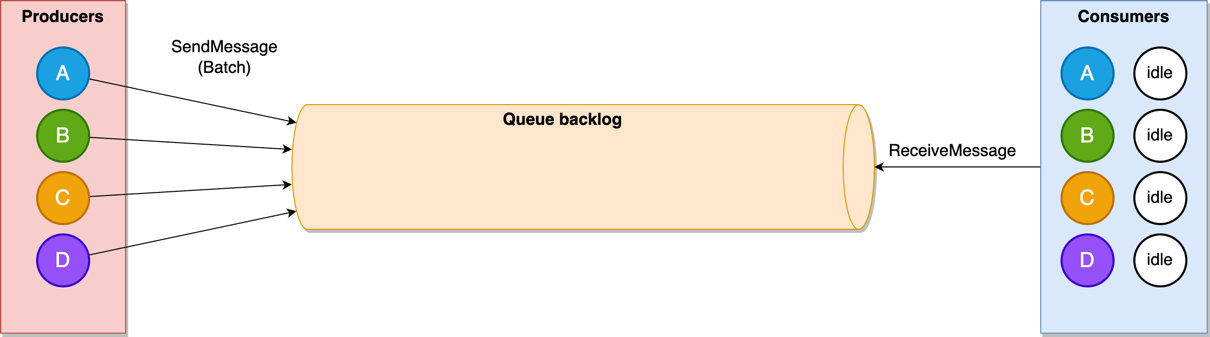
Consider the following example that consists of a multi-tenant queue and four different tenants (A, B, C, and D).

In the steady state condition, the queue has no backlog, and in-flight messages are evenly distributed among tenants. All messages are consumed immediately when they land in the queue. The dwell time of messages is low for all tenants. Notice that not all consumer capacity is fully utilized in this steady state. The steady state condition is illustrated in the following diagram.

Figure 1: A multi-tenant queue in steady state condition

Figure 1: A multi-tenant queue in steady state condition

Now consider a noisy tenant scenario in which the number of messages of tenant A increases significantly and creates a backlog in the queue. Consumers are busy processing the messages mostly from tenant A, and messages from other tenants are waiting in the backlog, leading to a higher dwell time for all tenants. This noisy tenant scenario is illustrated in the following screenshot.

Figure 2: A multi-tenant queue with a noisy tenant

Figure 2: A multi-tenant queue with a noisy tenant

When a single tenant starts to occupy a significant portion of consumer resources, Amazon SQS fair queues considers this tenant as a noisy neighbor and prioritizes returning messages belonging to other tenants. This prioritization helps maintain low dwell times for quiet tenants (B, C, D), while the dwell time for tenant A’s messages will be elevated until the queue backlog is consumed—but without impacting other tenants. Fair queues are illustrated in the following diagram.

Figure 3: A multi-tenant queue with fair queues

Figure 3: A multi-tenant queue with fair queues

Amazon SQS doesn’t limit the consumption rate per tenant. Consumers can receive messages from noisy neighbor tenants when there is consumer capacity and the queue has no other messages to return. Like Amazon SQS standard queues, fair queues allow virtually unlimited throughput, and there are no limits on the number of tenants you can have in your queue.

How to use

The following is a quick overview of how to get started with Amazon SQS fair queues in your applications. See the feature documentation for a detailed walkthrough. These are the high-level steps the walkthrough follows:

  1. Enable Amazon SQS fair queues by adding a tenant identifier (MessageGroupId) to your messages
  2. Configure Amazon CloudWatch metrics to monitor Amazon SQS fair queues behavior
  3. You can use the example application to observe the Amazon SQS fair queues behavior with varying message volumes

Enable Amazon SQS fair queues by adding a tenant identifier (MessageGroupId) to your messages

Your message producers can add a tenant identifier by setting a MessageGroupId on an outgoing message:

// Send message with tenant identifier
SendMessageRequest request = new SendMessageRequest()
    .withQueueUrl(queueUrl)
    .withMessageBody(messageBody)
    .withMessageGroupId("tenant-123");  // Tenant identifier
sqs.sendMessage(request);

The new fairness capability will be applied automatically in all Amazon SQS standard queues for messages with the MessageGroupId property. It’s important to mention that it doesn’t require any change in the consumer code. It has no impact on API latency and doesn’t come with any throughput limitations.

Configure Amazon CloudWatch metrics to monitor Amazon SQS fair queues behavior

You can monitor Amazon SQS fair queues with Amazon CloudWatch metrics. The following terms are important in this context:

  • Noisy groups – A noisy message group represents a noisy neighbor tenant of a multi-tenant queue.
  • Quiet groups – Message groups excluding noisy groups.

When you use fair queues, Amazon SQS now emits the following additional metrics:

  • ApproximateNumberOfNoisyGroups
  • ApproximateNumberOfMessagesVisibleInQuietGroups
  • ApproximateNumberOfMessagesNotVisibleInQuietGroups
  • ApproximateNumberOfMessagesDelayedInQuietGroups
  • ApproximateAgeOfOldestMessageInQuietGroups

The new ApproximateNumberOfNoisyGroups metric gives the number of message groups (tenants) that are considered noisy in a fair queue. This metric helps identify the number of potential noisy neighbors in multi-tenant environments by tracking message groups consuming disproportionate resources. Use this metric to set alarms that trigger when the number of noisy groups exceeds your acceptable threshold, indicating potential queue fairness issues.

Amazon SQS already provides several standard queue-level metrics that offer approximate insights into the queue’s state, message processing, and potential bottlenecks. These metrics look at all messages in a queue. With fair queues, there’s a new set of four equivalent metrics, shown in the preceding list, that allow the exclusion of messages from noisy neighbor groups and target only quiet groups (non-noisy tenants). Hence, they all have the InQuietGroups suffix.

To monitor the effect of Amazon SQS fair queues you can compare metrics that have the InQuietGroups suffix with standard queue-level metrics. During traffic surges for a specific tenant, the general queue-level metrics might reveal increasing backlogs or older message ages. However, looking at the quiet groups in isolation, you can identify that most non-noisy message groups or tenants aren’t impacted, and you can estimate the total number of impacted message groups.

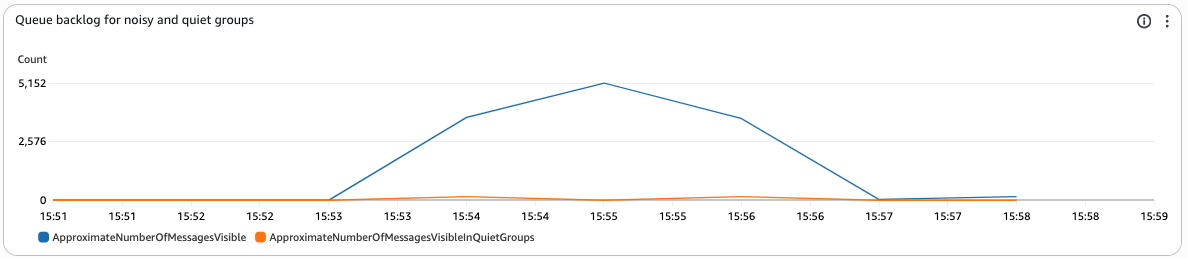
The following graph shows how the standard queue backlog metric (ApproximateNumberOfMessagesVisible) increases due to a noisy tenant while the backlog for non-noisy tenants (ApproximateNumberOfMessagesVisibleInQuietGroups) remains low.

Figure 4: Queue backlog for noisy and quiet groups

Figure 4: Queue backlog for noisy and quiet groups

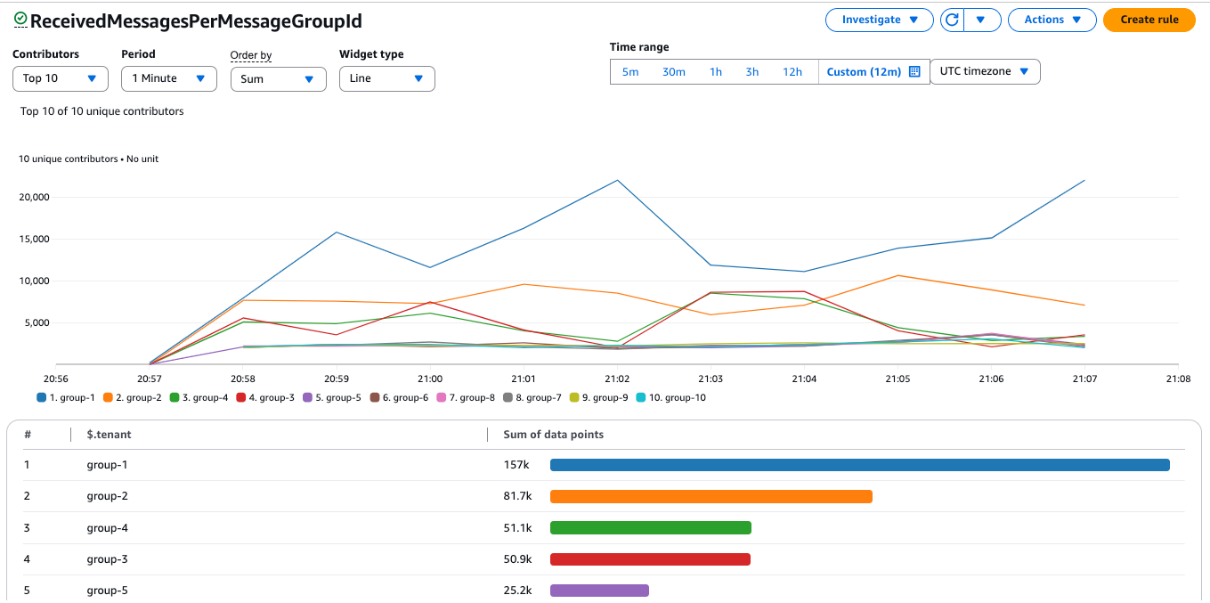
While these new metrics provide a good overview of Amazon SQS fair queues behavior, it can be beneficial to understand which specific tenant is causing the load. Use Amazon CloudWatch Contributor Insights to see metrics about the top-N contributors, the total number of unique contributors, and their usage. This is especially helpful in scenarios where you’re dealing with thousands of tenants that would otherwise lead to high-cardinality data (and cost) when emitting traditional metrics. The following screenshot shows an example of a Contributor Insights dashboard on the AWS console that visualizes the top 10 contributors based on MessageGroupId.

Figure 5: Container Insights ReceivedMessagesPerMessageGroupId dashboard

Figure 5: Container Insights ReceivedMessagesPerMessageGroupId dashboard

Contributor Insights creates these metrics based on data from your application log output. Let your code log the number of messages being processed, and the corresponding MessageGroupId within your application. You can find a full example in the sample application in the next section.

Example application

To make it even more straightforward to get started, we’ve prepared an example application that you can use to observe the Amazon SQS fair queues behavior with varying message volumes. You can find the source code repository, infrastructure as code (IaC), and the instructions to run the sample on the sqs-fair-queues repository on GitHub.

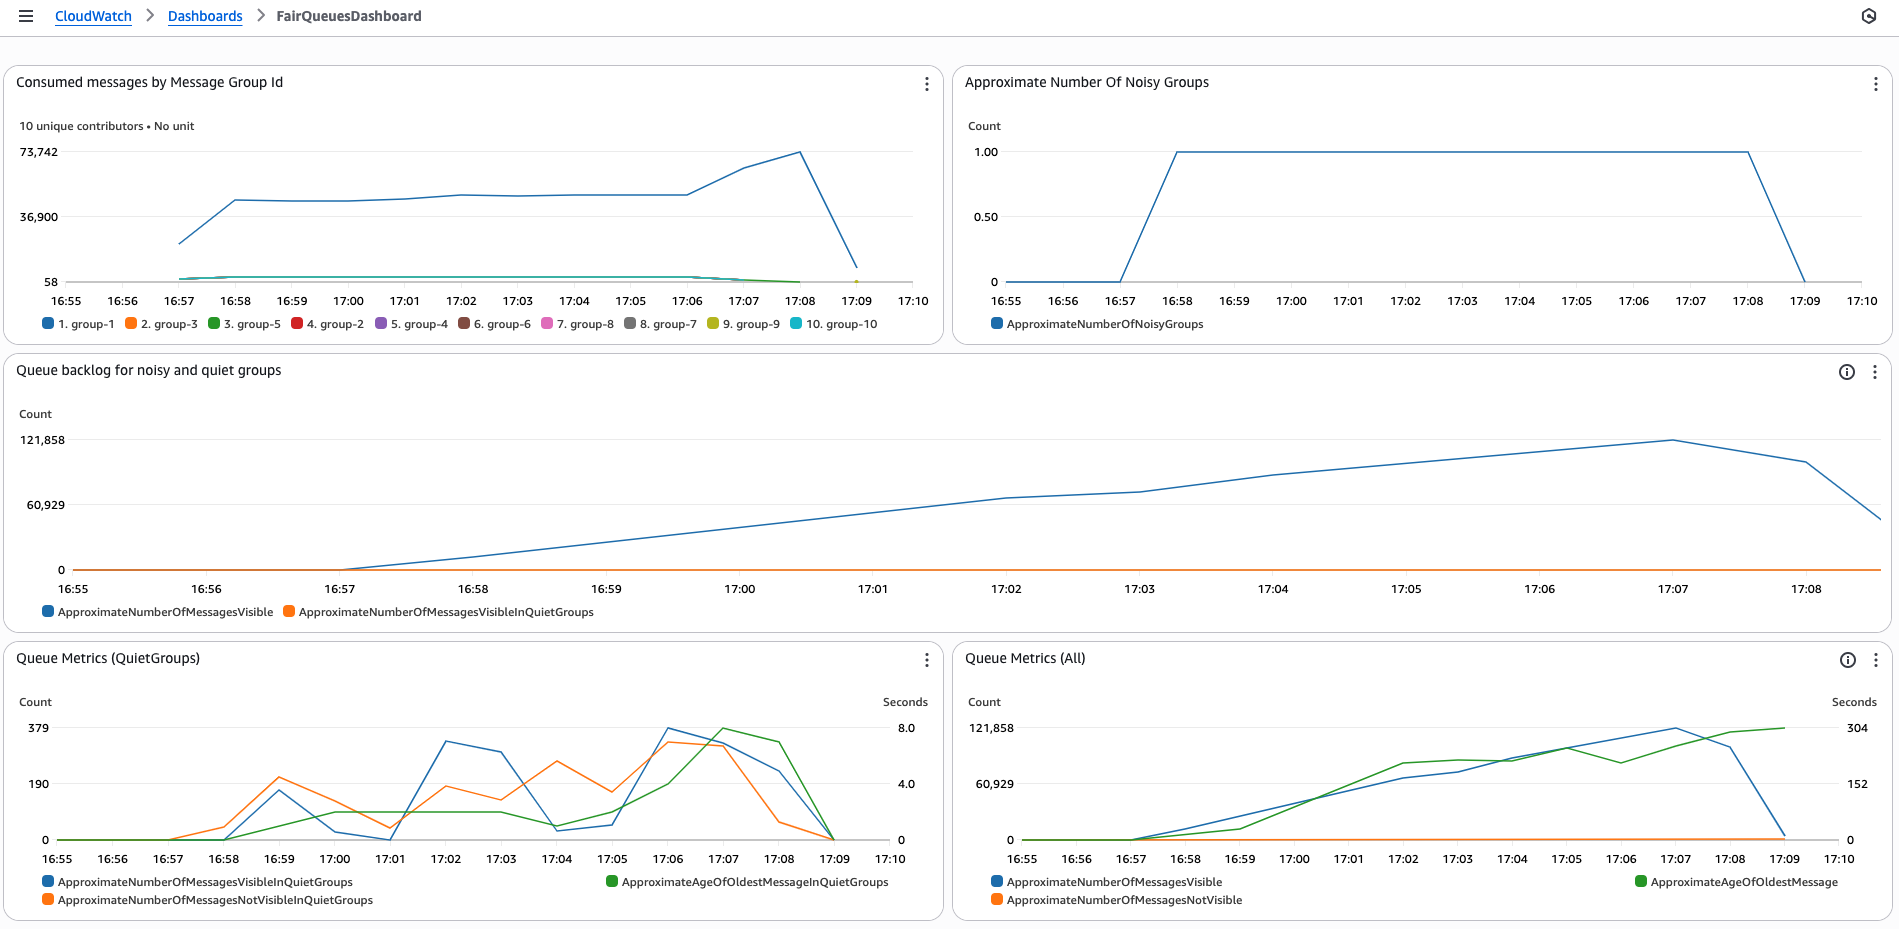
The example application includes a load generator to simulate multi-tenant traffic and provides an Amazon CloudWatch dashboard that displays the most important metrics to visualize fair queue behavior. The following screenshot shows an example of the dashboard.


Figure 6: CloudWatch FairQueuesDashboard

Conclusion

Amazon SQS fair queues automatically mitigates the noisy neighbor impact in multi-tenant queues. Even when one tenant generates high message volumes or requires longer processing times (that is, becomes a noisy neighbor), the feature maintains consistent message dwell times for other tenants. When you add a tenant identifier to your messages, Amazon SQS fair queues will automatically detect and mitigate noisy neighbor impact, providing fair access to the queue for other tenants.

We recommend reviewing the Amazon SQS Developer Guide to get started and exploring the sample applications to test the behavior with varying message volumes.

Optimizing vector search using Amazon S3 Vectors and Amazon OpenSearch Service

Post Syndicated from Sohaib Katariwala original https://aws.amazon.com/blogs/big-data/optimizing-vector-search-using-amazon-s3-vectors-and-amazon-opensearch-service/

NOTE: As of July 15, the Amazon S3 Vectors Integration with Amazon OpenSearch Service is in preview release and is subject to change.

The way we store and search through data is evolving rapidly with the advancement of vector embeddings and similarity search capabilities. Vector search has become essential for modern applications such as generative AI and agentic AI, but managing vector data at scale presents significant challenges. Organizations often struggle with the trade-offs between latency, cost, and accuracy when storing and searching through millions or billions of vector embeddings. Traditional solutions either require substantial infrastructure management or come with prohibitive costs as data volumes grow.

We now have a public preview of two integrations between Amazon Simple Storage Service (Amazon S3) Vectors and Amazon OpenSearch Service that give you more flexibility in how you store and search vector embeddings:

  1. Cost-optimized vector storage: OpenSearch Service managed clusters using service-managed S3 Vectors for cost-optimized vector storage. This integration will support OpenSearch workloads that are willing to trade off higher latency for ultra-low cost and still want to use advanced OpenSearch capabilities (such as hybrid search, advanced filtering, geo filtering, and so on).
  2. One-click export from S3 Vectors: One-click export from an S3 vector index to OpenSearch Serverless collections for high-performance vector search. Customers who build natively on S3 Vectors will benefit from being able to use OpenSearch for faster query performance.

By using these integrations, you can optimize cost, latency, and accuracy by intelligently distributing your vector workloads by keeping infrequent queried vectors in S3 Vectors and using OpenSearch for your most time-sensitive operations that require advanced search capabilities such as hybrid search and aggregations. Further, OpenSearch performance tuning capabilities (that is, quantization, k-nearest neighbor (knn) algorithms, and method-specific parameters) help to improve the performance with little compromise of cost or accuracy.

In this post, we walk through this seamless integration, providing you with flexible options for vector search implementation. You’ll learn how to use the new S3 Vectors engine type in OpenSearch Service managed clusters for cost-optimized vector storage and how to use one-click export from S3 Vectors to OpenSearch Serverless collections for high-performance scenarios requiring sustained queries with latency as low as 10ms. By the end of this post, you’ll understand how to choose and implement the right integration pattern based on your specific requirements for performance, cost, and scale.

Service overview

Amazon S3 Vectors is the first cloud object store with native support to store and query vectors with sub-second search capabilities, requiring no infrastructure management. It combines the simplicity, durability, availability, and cost-effectiveness of Amazon S3 with native vector search functionality, so you can store and query vector embeddings directly in S3. Amazon OpenSearch Service provides two complementary deployment options for vector workloads: Managed Clusters and Serverless Collections. Both harness Amazon OpenSearch’s powerful vector search and retrieval capabilities, though each excels in different scenarios. For OpenSearch users, the integration between S3 Vectors and Amazon OpenSearch Service offers unprecedented flexibility in optimizing your vector search architecture. Whether you need ultra-fast query performance for real-time applications or cost-effective storage for large-scale vector datasets, this integration lets you choose the approach that best fits your specific use case.

Understanding Vector Storage Options

OpenSearch Service provides multiple options for storing and searching vector embeddings, each optimized for different use cases. The Lucene engine, which is OpenSearch’s native search library, implements the Hierarchical Navigable Small World (HNSW) method, offering efficient filtering capabilities and strong integration with OpenSearch’s core functionality. For workloads requiring additional optimization options, the Faiss engine (Facebook AI Similarity Search) provides implementations of both HNSW and IVF (Inverted File Index) methods, along with vector compression capabilities. HNSW creates a hierarchical graph structure of connections between vectors, enabling efficient navigation during search, while IVF organizes vectors into clusters and searches only relevant subsets during query time. With the introduction of the S3 engine type, you now have a cost-effective option that uses Amazon S3’s durability and scalability while maintaining sub-second query performance. With this variety of options, you can choose the most suitable approach based on your specific requirements for performance, cost, and accuracy. For instance, if your application requires sub-50 ms query responses with efficient filtering, Faiss’s HNSW implementation is the best choice. Alternatively, if you need to optimize storage costs while maintaining reasonable performance, the new S3 engine type would be more appropriate.

Solution overview

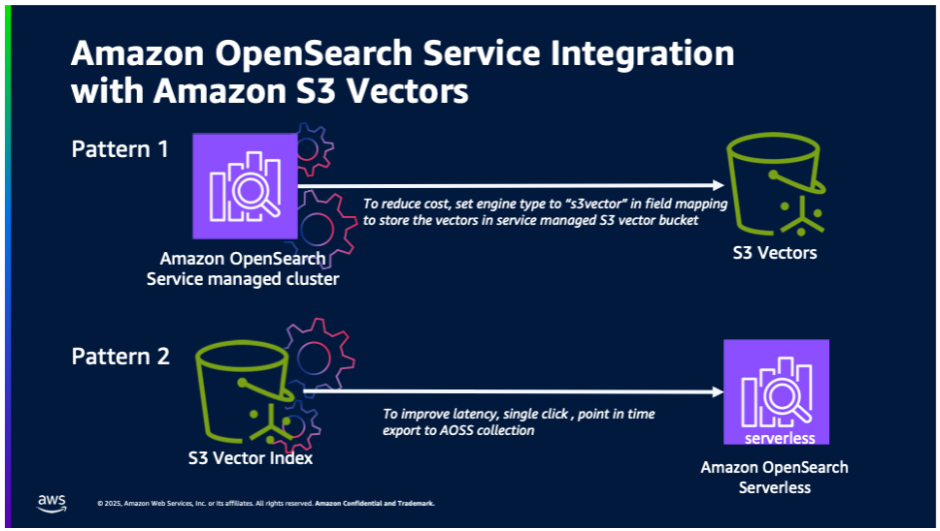
In this post, we explore two primary integration patterns:

OpenSearch Service managed clusters using service-managed S3 Vectors for cost-optimized vector storage.

For customers already using OpenSearch Service domains who want to optimize costs while maintaining sub-second query performance, the new Amazon S3 engine type offers a compelling solution. OpenSearch Service automatically manages vector storage in Amazon S3, data retrieval, and cache optimization, eliminating operational overhead.

One-click export from an S3 vector index to OpenSearch Serverless collections for high-performance vector search.

For use cases requiring faster query performance, you can migrate your vector data from an S3 vector index to an OpenSearch Serverless collection. This approach is ideal for applications that require real-time response times and gives you the benefits that come with Amazon OpenSearch Serverless, including advanced query capabilities and filters, automatic scaling and high availability, and no administration. The export process automatically handles schema mapping, vector data transfer, index optimization, and connection configuration.

The following illustration shows the two integration patterns between Amazon OpenSearch Service and S3 Vectors.

Prerequisites

Before you begin, make sure you have:

  • An AWS account
  • Access to Amazon S3 and Amazon OpenSearch Service
  • An OpenSearch Service domain (for the first integration pattern)
  • Vector data stored in S3 Vectors (for the second integration pattern)

Integration pattern 1: OpenSearch Service managed cluster using S3 Vectors

To implement this pattern:

  1. Create an OpenSearch Service Domain using OR1 instances on OpenSearch version 2.19.
    1. While creating the OpenSearch Service domain, choose the Enable S3 Vectors as an engine option in the Advanced features section.
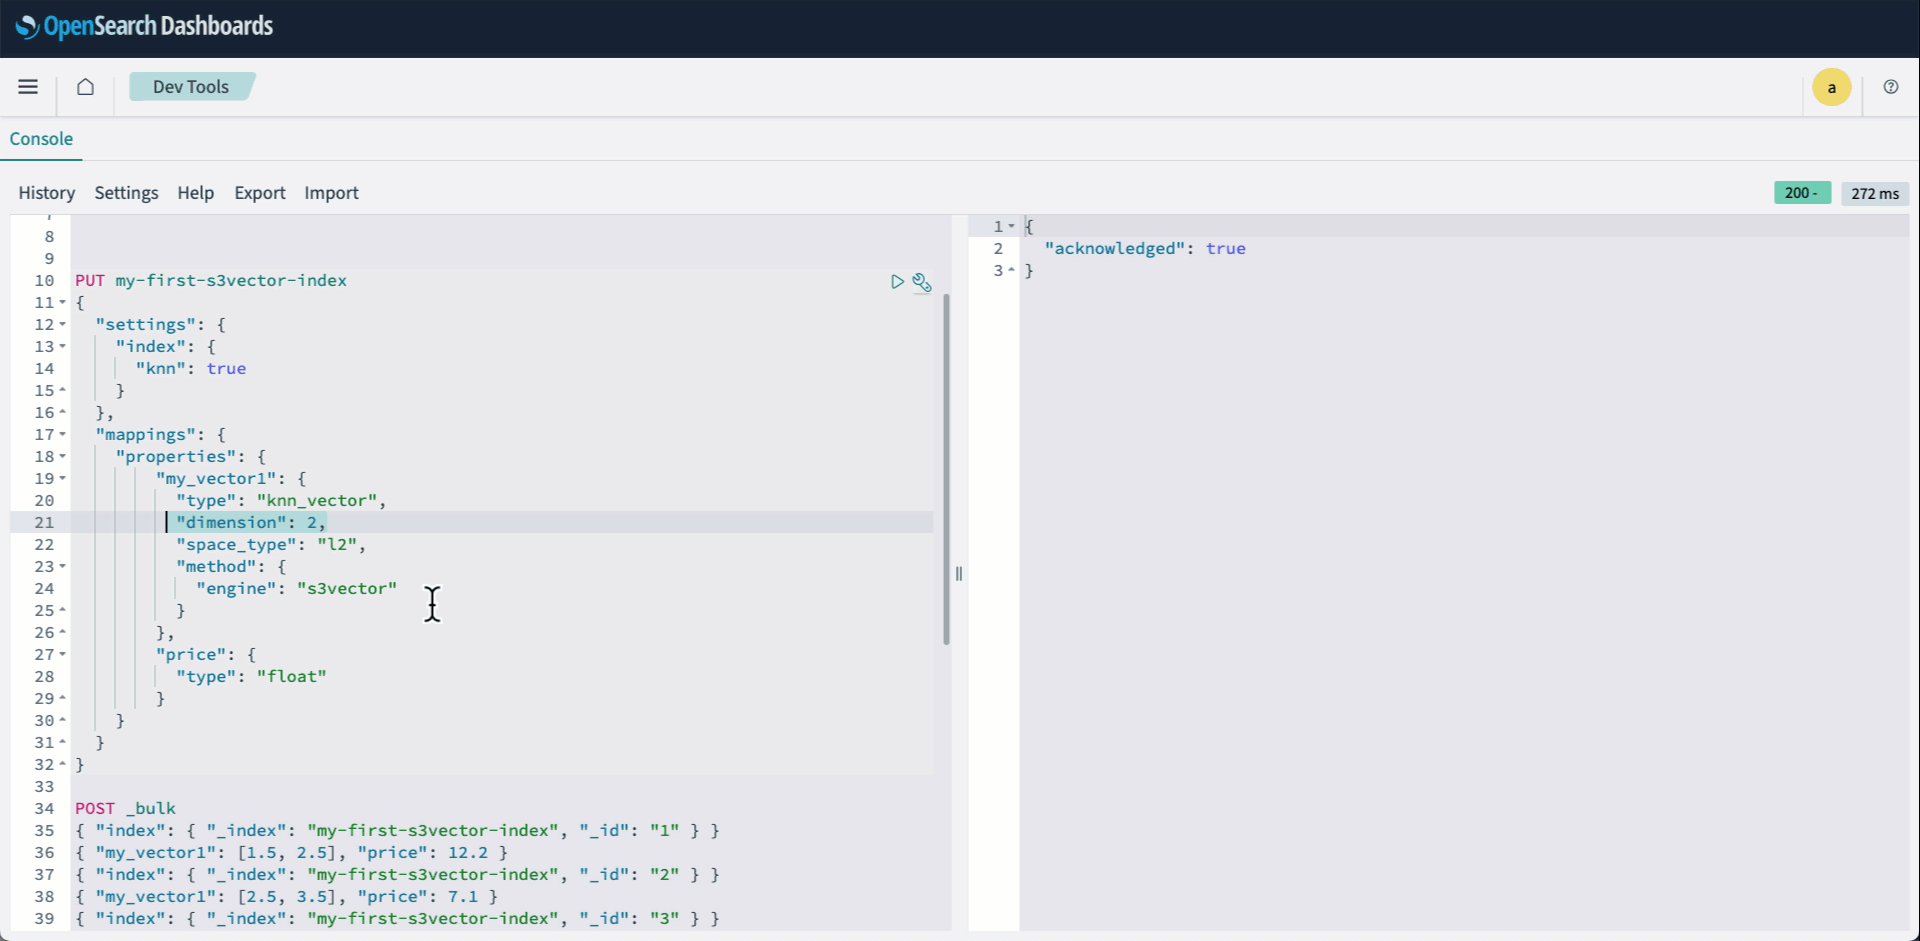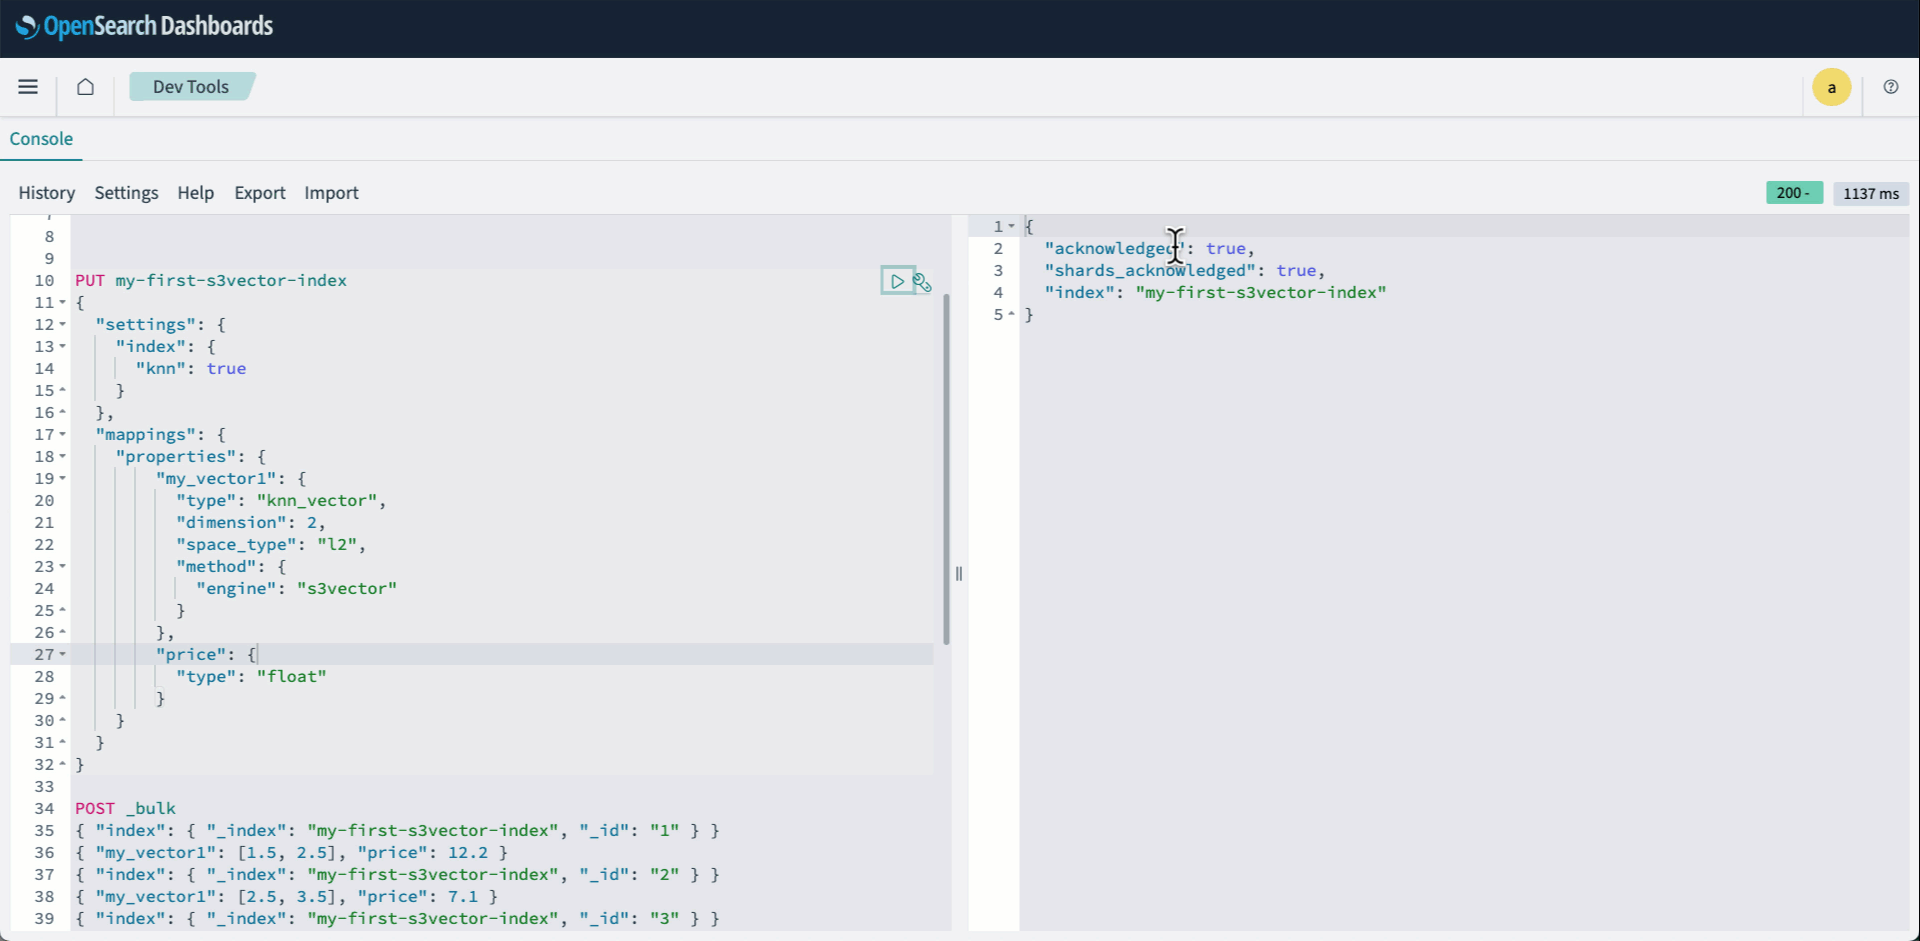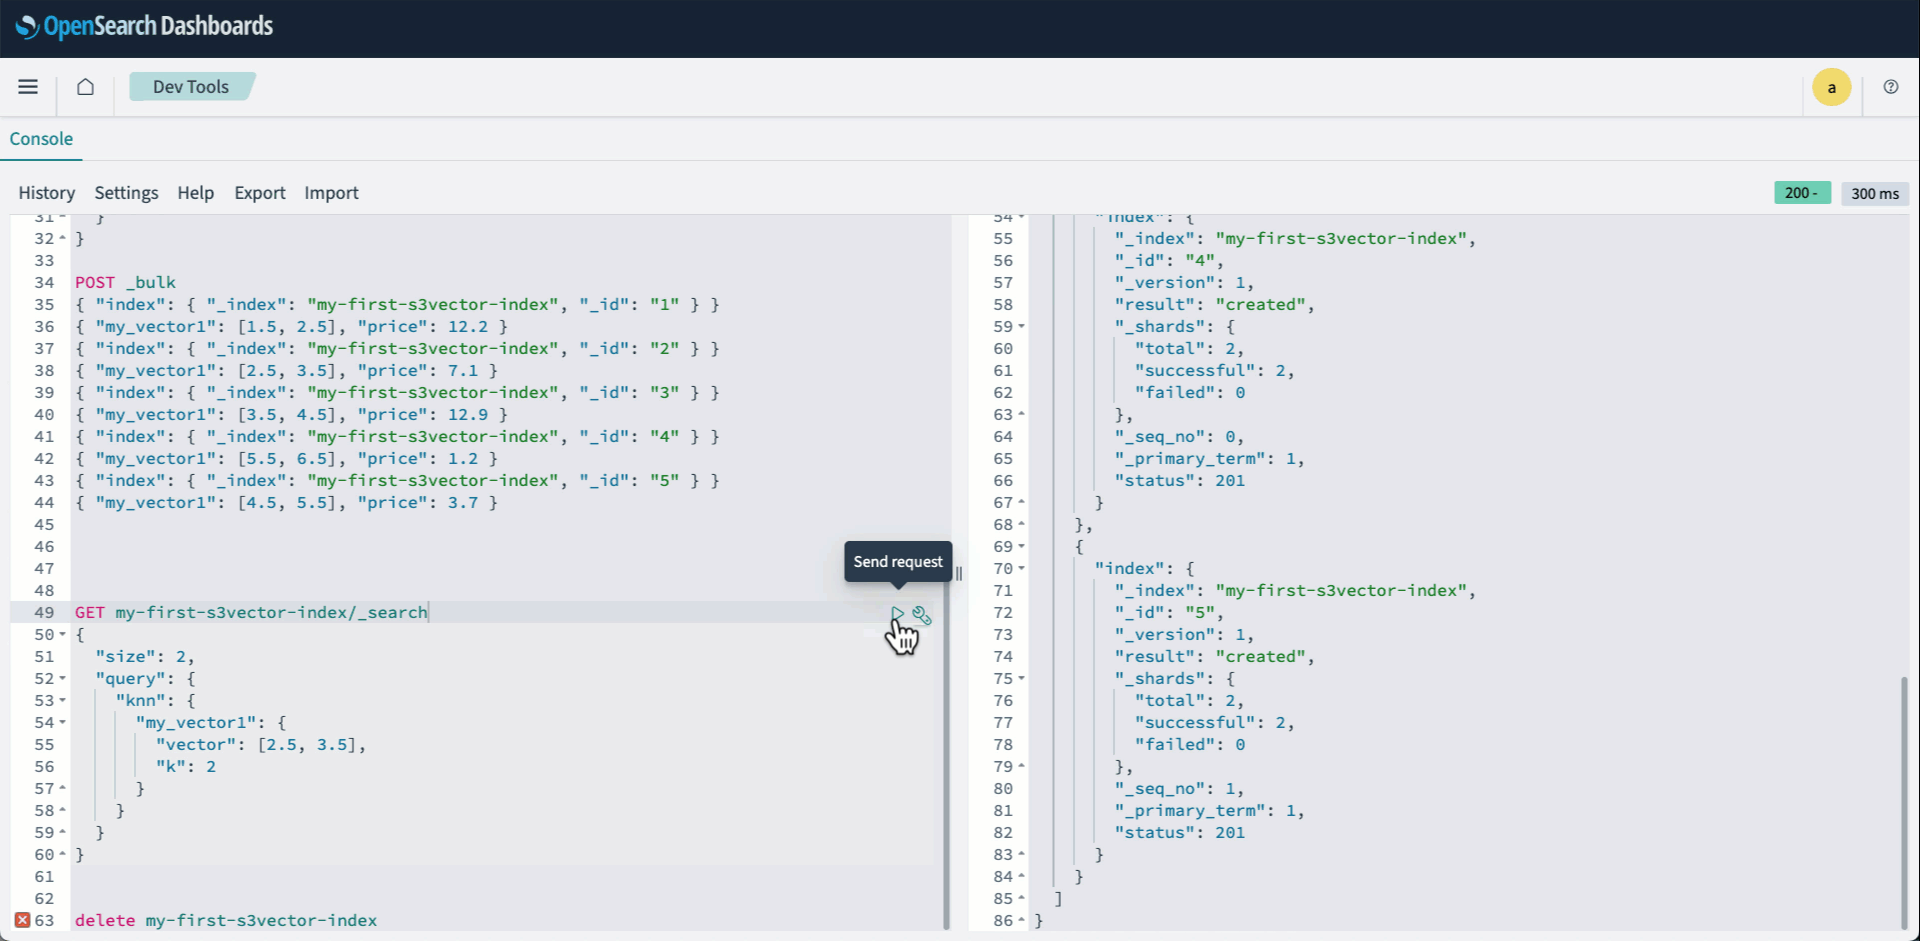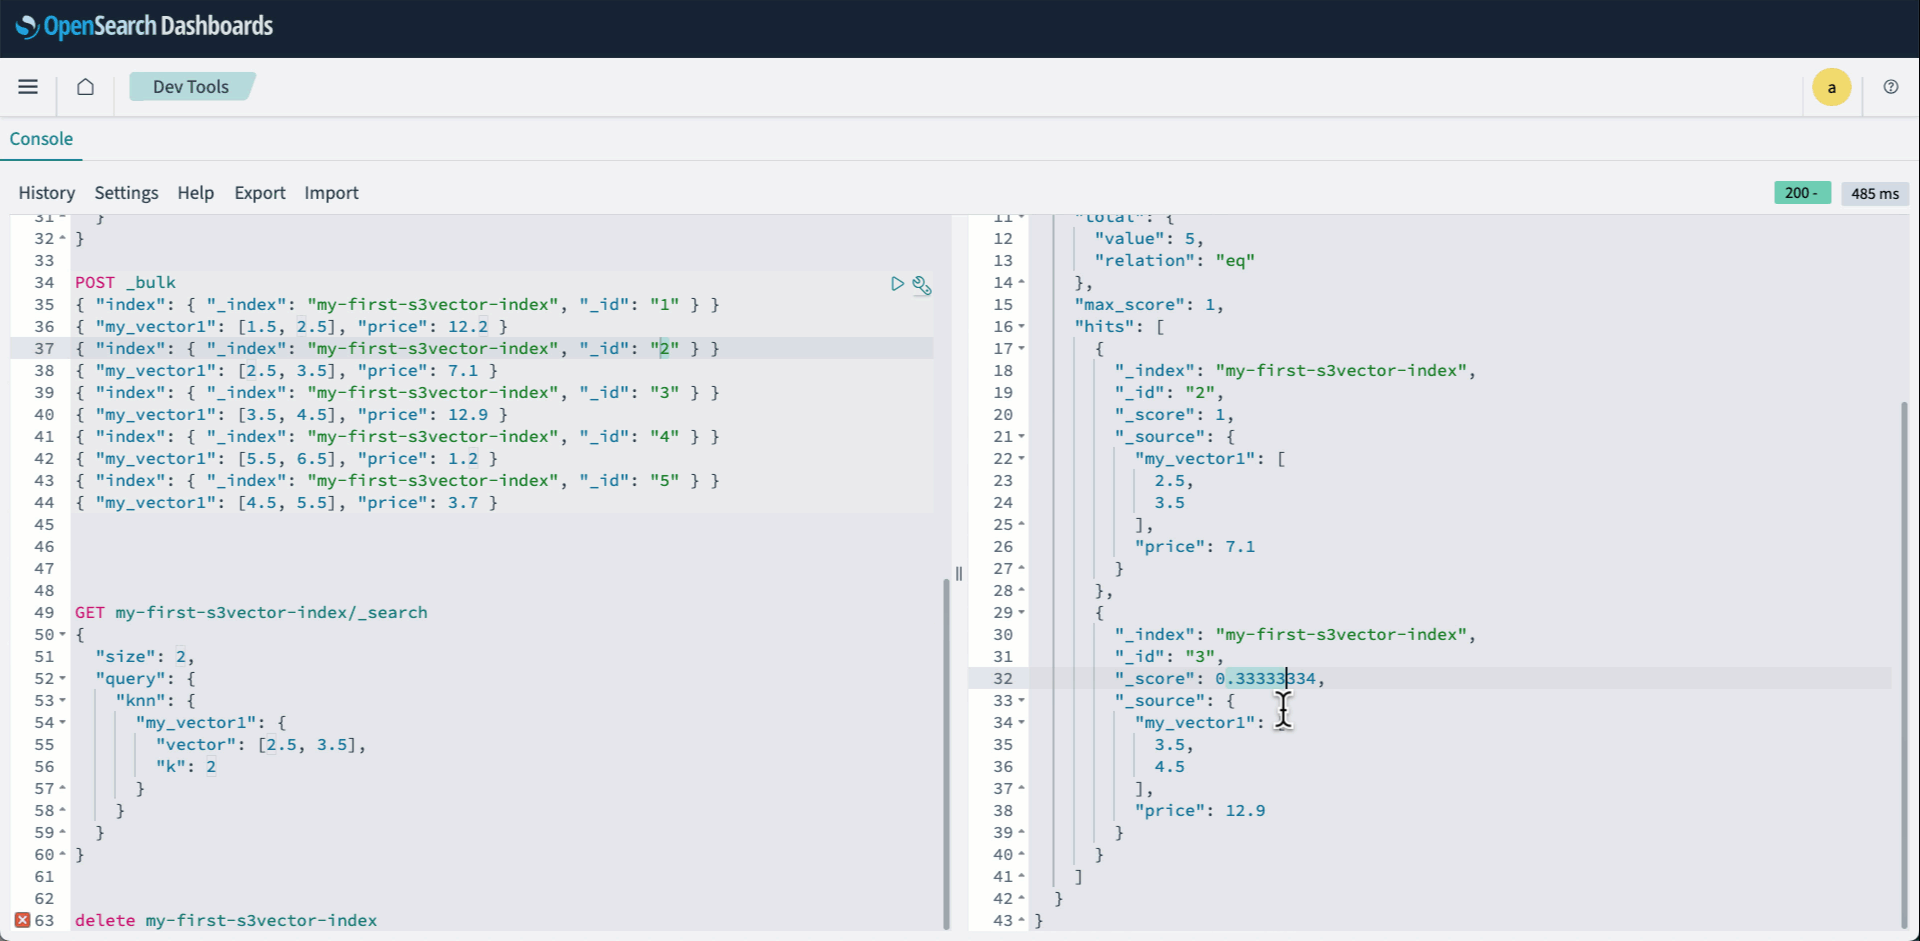
  2. Sign in to OpenSearch Dashboards and open Dev tools. Then create your knn index and specify s3vector as the engine.
PUT my-first-s3vector-index
{
  "settings": {
    "index": {
      "knn": true
    }
  },
  "mappings": {
    "properties": {
        "my_vector1": {
          "type": "knn_vector",
          "dimension": 2,
          "space_type": "l2",
          "method": {
            "engine": "s3vector"
          }
        },
        "price": {
          "type": "float"
        }
    }
  }
} 
  1. Index your vectors using the Bulk API:
POST _bulk
{ "index": { "_index": "my-first-s3vector-index", "_id": "1" } }
{ "my_vector1": [2.5, 3.5], "price": 7.1 }
{ "index": { "_index": "my-first-s3vector-index", "_id": "3" } }
{ "my_vector1": [3.5, 4.5], "price": 12.9 }
{ "index": { "_index": "my-first-s3vector-index", "_id": "4" } }
{ "my_vector1": [5.5, 6.5], "price": 1.2 }
{ "index": { "_index": "my-first-s3vector-index", "_id": "5" } }
{ "my_vector1": [4.5, 5.5], "price": 3.7 }
{ "index": { "_index": "my-first-s3vector-index", "_id": "6" } }
{ "my_vector1": [1.5, 2.5], "price": 12.2 }
  1. Run a knn query as usual:
GET my-first-s3vector-index/_search
{
  "size": 2,
  "query": {
    "knn": {
      "my_vector1": {
        "vector": [2.5, 3.5],
        "k": 2
      }
    }
  }
}

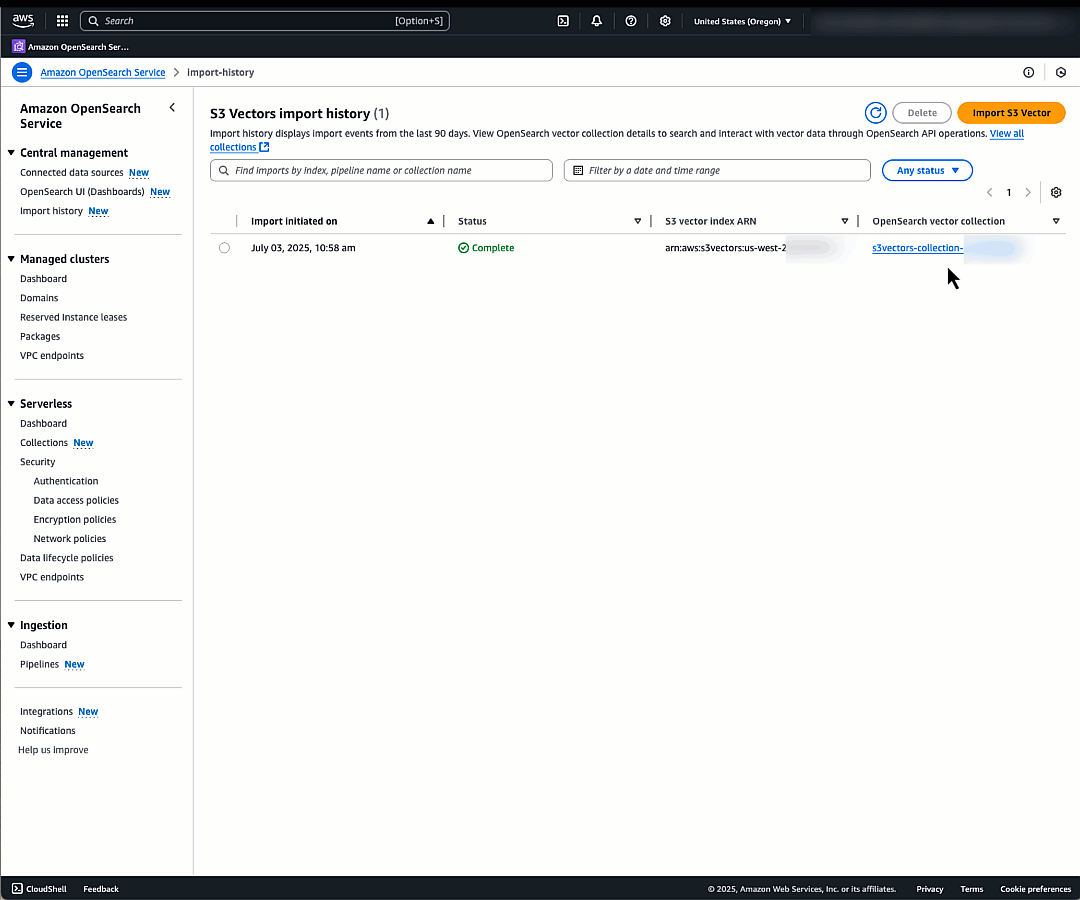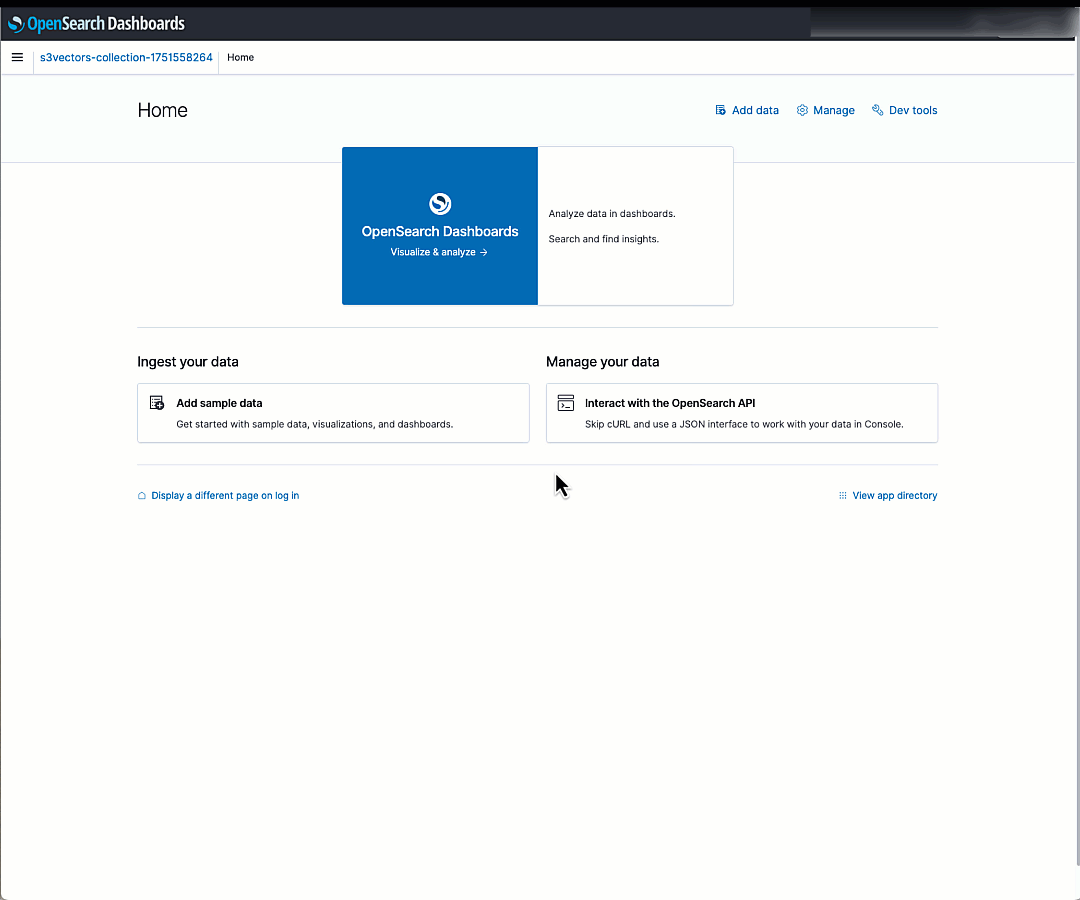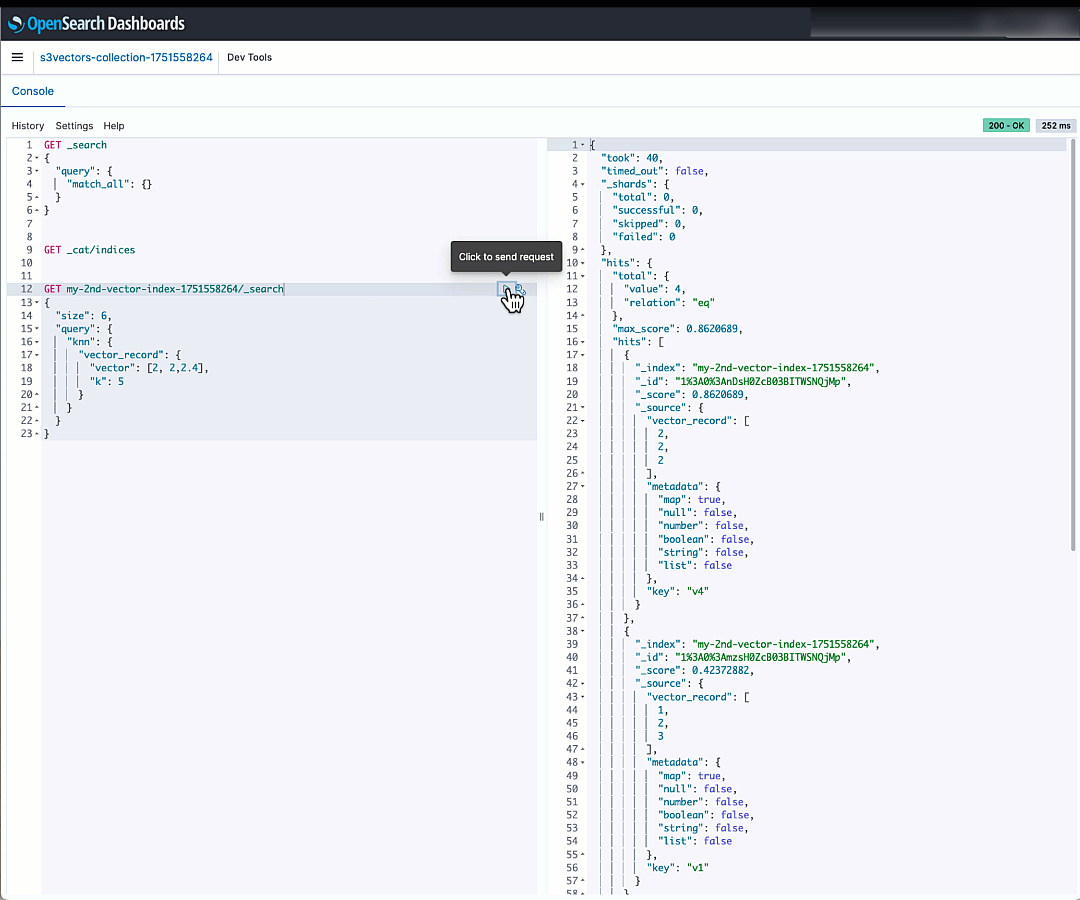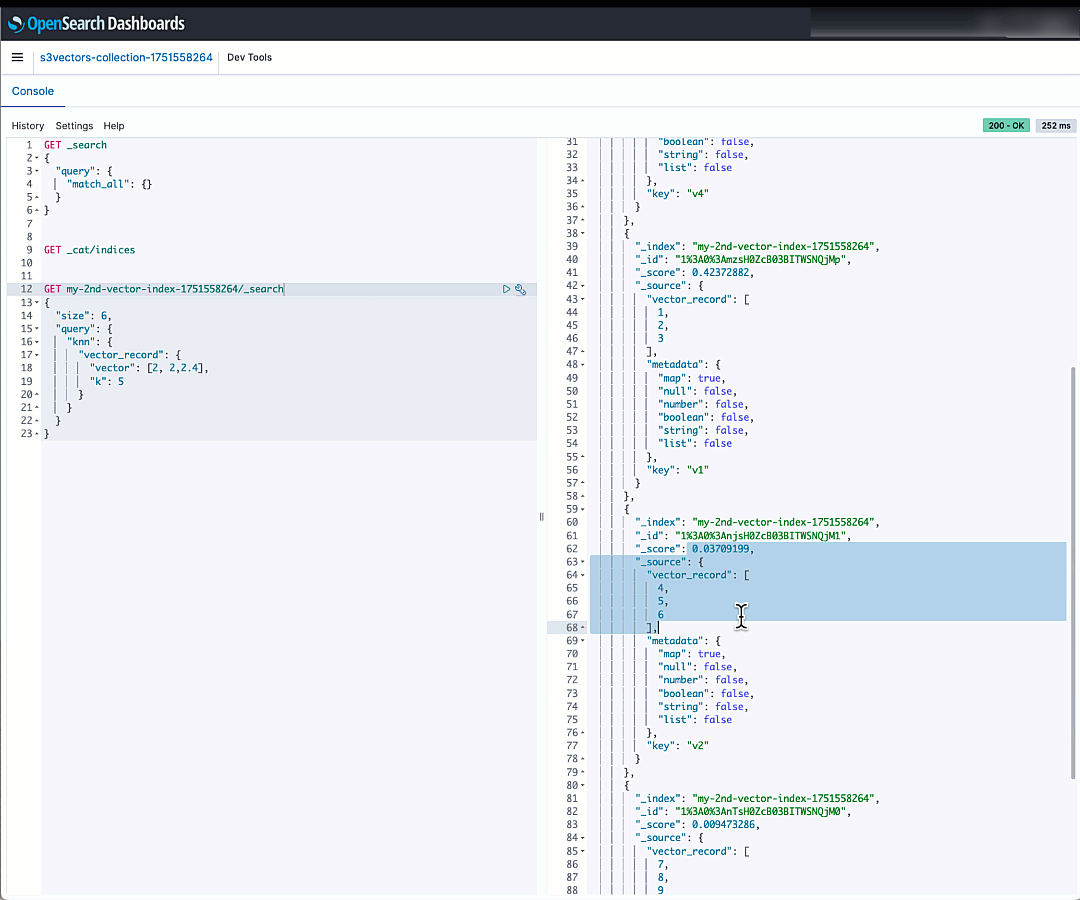
The following animation demonstrates steps 2-4 above.

Integration pattern 2: Export S3 vector indexes to OpenSearch Serverless

To implement this pattern:

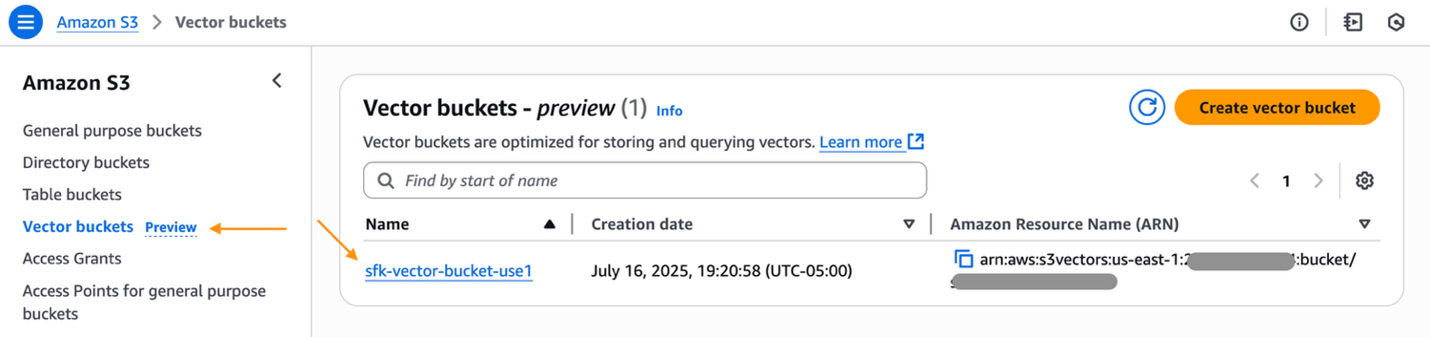
  1. Navigate to the AWS Management Console for Amazon S3 and select your S3 vector bucket.

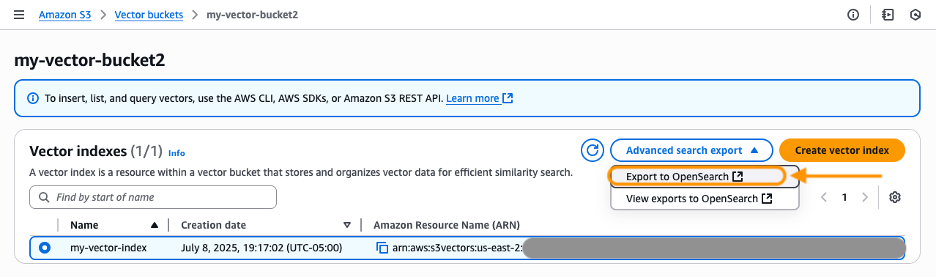
  1. Select a vector index that you want to export. Under Advanced search export, select Export to OpenSearch.

Alternatively, you can:

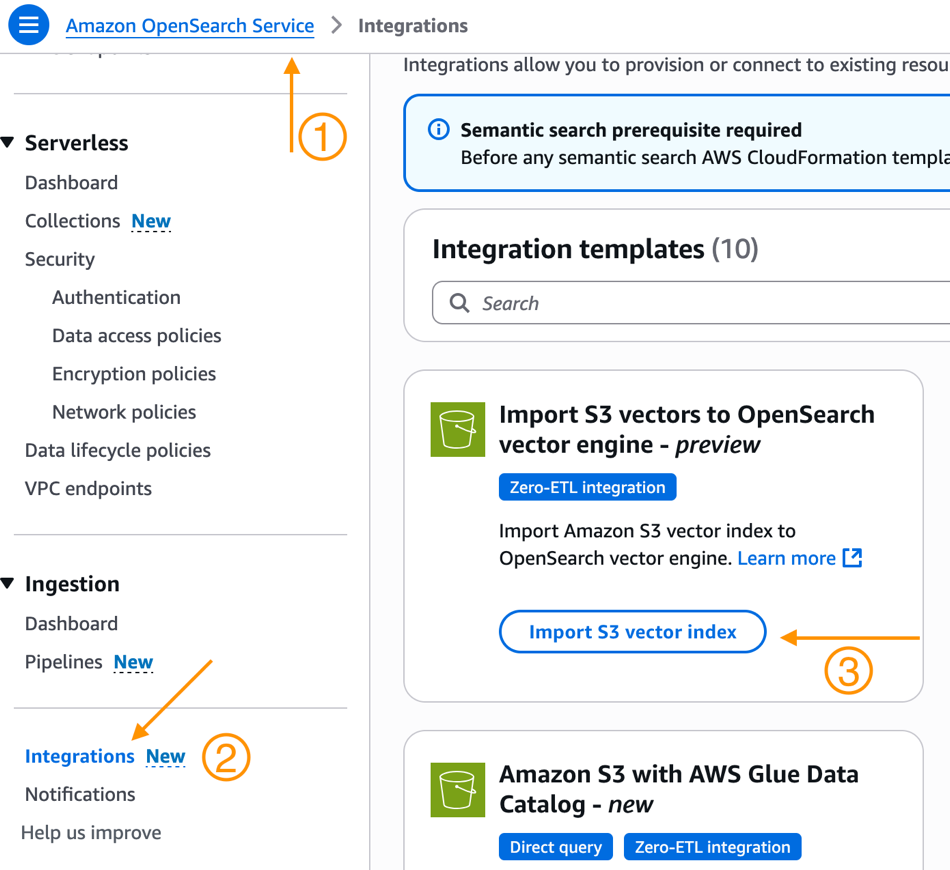
  1. Navigate to the OpenSearch Service console.
  2. Select Integrations from the navigation pane.
  3. Here you will see a new Integration Template to Import S3 vectors to OpenSearch vector engine – preview. Select Import S3 vector index.

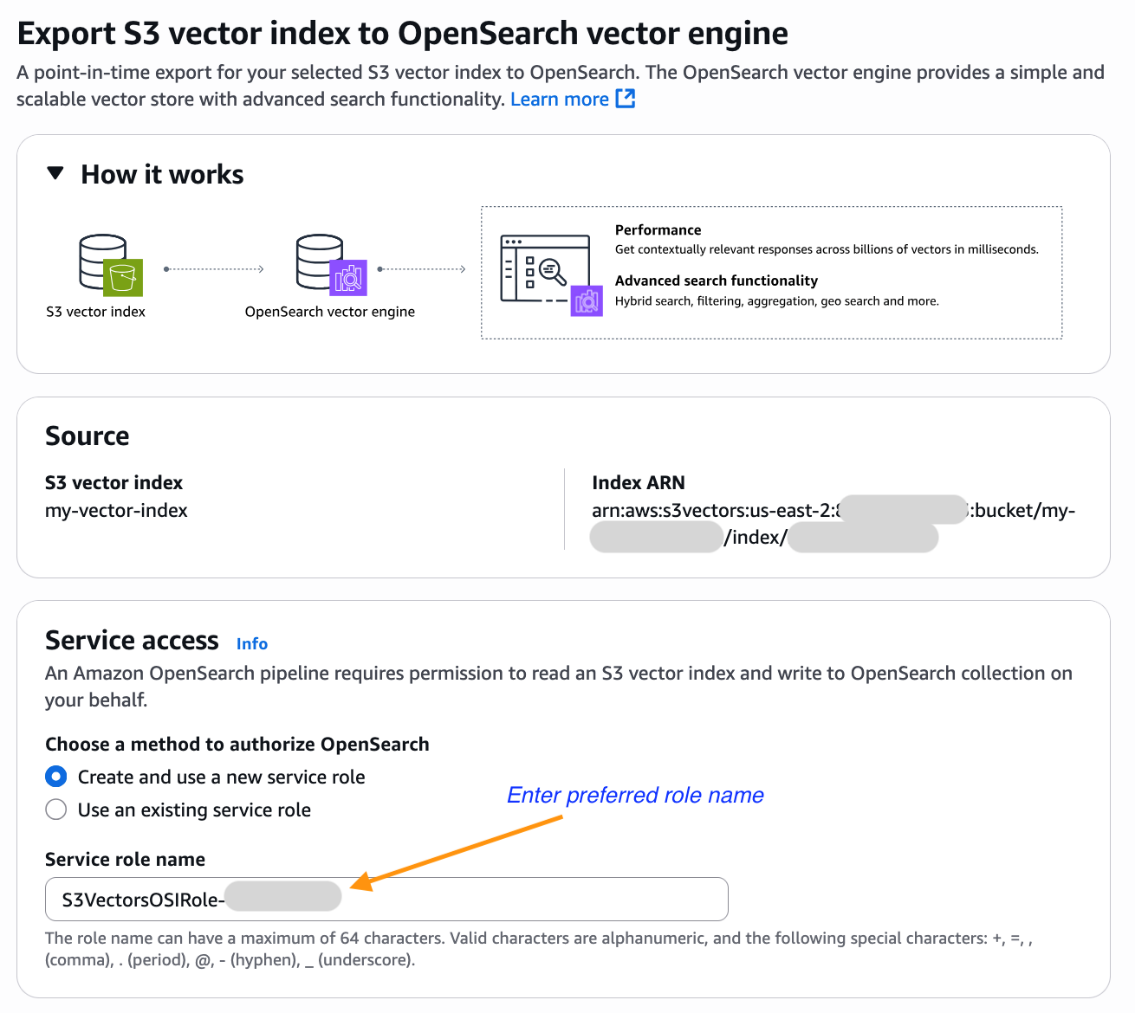
  1. You will now be brought to the Amazon OpenSearch Service integration console with the Export S3 vector index to OpenSearch vector engine template pre-selected and pre-populated with your S3 vector index Amazon Resource Name (ARN). Select an existing role that has the necessary permissions or create a new service role.

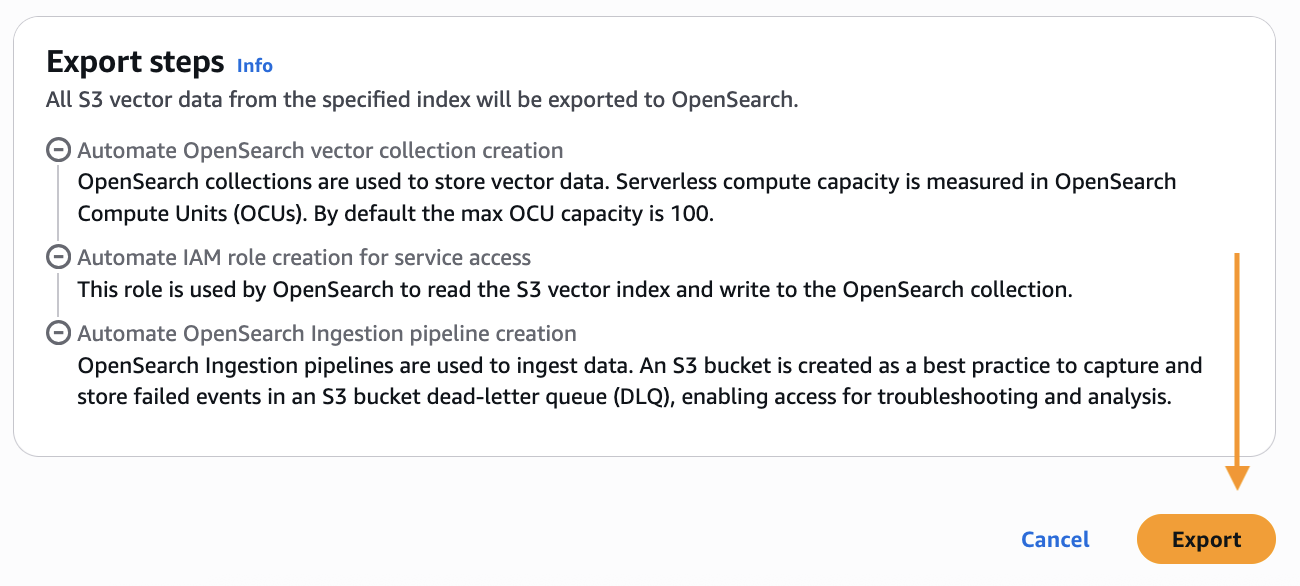
  1. Scroll down and choose Export to start the steps to create a new OpenSearch Serverless collection and copy data from your S3 vector index into an OpenSearch knn index.

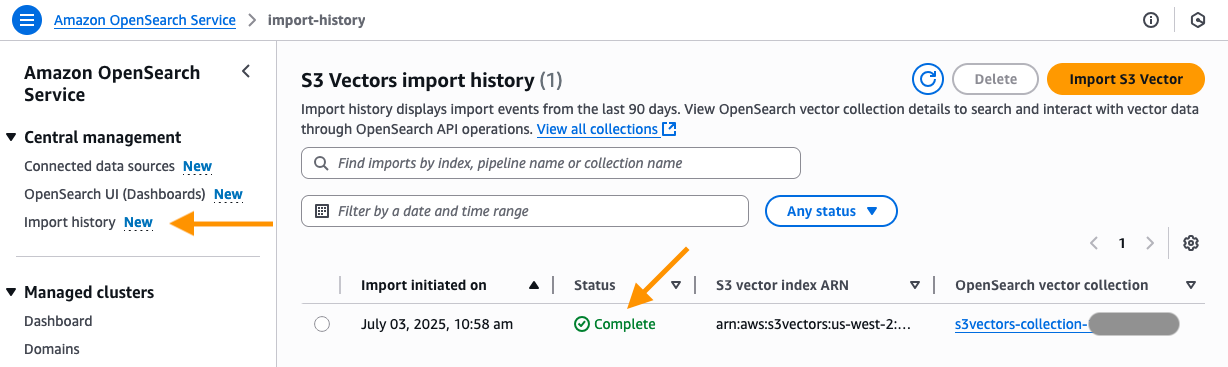
  1. You will now be taken to the Import history page in the OpenSearch Service console. Here you will see the new job that was created to migrate your S3 vector index into the OpenSearch serverless knn index. After the status changes from In Progress to Complete, you can connect to the new OpenSearch serverless collection and query your new OpenSearch knn index.

The following animation demonstrates how to connect to the new OpenSearch serverless collection and query your new OpenSearch knn index using Dev tools.

Cleanup

To avoid ongoing charges:

  1. For Pattern 1:
  1. For Pattern 2:
    • Delete the import task from the Import history section of the OpenSearch Service console. Deleting this task will remove both the OpenSearch vector collection and the OpenSearch Ingestion pipeline that was automatically created by the import task.

Conclusion

The innovative integration between Amazon S3 Vectors and Amazon OpenSearch Service marks a transformative milestone in vector search technology, offering unprecedented flexibility and cost-effectiveness for enterprises. This powerful combination delivers the best of both worlds: The renowned durability and cost efficiency of Amazon S3 merged seamlessly with the advanced AI search capabilities of OpenSearch. Organizations can now confidently scale their vector search solutions to billions of vectors while maintaining control over their latency, cost, and accuracy. Whether your priority is ultra-fast query performance with latency as low as 10ms through OpenSearch Service, or cost-optimized storage with impressive sub-second performance using S3 Vectors or implementing advanced search capabilities in OpenSearch, this integration provides the perfect solution for your specific needs. We encourage you to get started today by trying S3 Vectors engine in your OpenSearch managed clusters and testing the one-click export from S3 vector indexes to OpenSearch Serverless.

For more information, visit:


About the Authors

Sohaib Katariwala is a Senior Specialist Solutions Architect at AWS focused on Amazon OpenSearch Service based out of Chicago, IL. His interests are in all things data and analytics. More specifically he loves to help customers use AI in their data strategy to solve modern day challenges.

Mark Twomey is a Senior Solutions Architect at AWS focused on storage and data management. He enjoys working with customers to put their data in the right place, at the right time, for the right cost. Living in Ireland, Mark enjoys walking in the countryside, watching movies, and reading books.

Sorabh Hamirwasia is a senior software engineer at AWS working on the OpenSearch Project. His primary interest include building cost optimized and performant distributed systems.

Pallavi Priyadarshini is a Senior Engineering Manager at Amazon OpenSearch Service leading the development of high-performing and scalable technologies for search, security, releases, and dashboards.

Bobby Mohammed is a Principal Product Manager at AWS leading the Search, GenAI, and Agentic AI product initiatives. Previously, he worked on products across the full lifecycle of machine learning, including data, analytics, and ML features on SageMaker platform, deep learning training and inference products at Intel.
AWS Weekly Roundup: Kiro, AWS Lambda remote debugging, Amazon ECS blue/green deployments, Amazon Bedrock AgentCore, and more (July 21, 2025)

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-kiro-aws-lambda-remote-debugging-amazon-ecs-blue-green-deployments-amazon-bedrock-agentcore-and-more-july-21-2025/

I’m writing this as I depart from Ho Chi Minh City back to Singapore. Just realized what a week it’s been, so let me rewind a bit. This week, I tried my first Corne keyboard, wrapped up rehearsals for AWS Summit Jakarta with speakers who are absolutely raising the bar, and visited Vietnam to participate as a technical keynote speaker in AWS Community Day Vietnam, an energetic gathering of hundreds of cloud practitioners and AWS enthusiasts who shared knowledge through multiple technical tracks and networking sessions.

What I presented was a keynote titled “Reinvent perspective as modern developers”, featuring serverless, containers, and how we can cut the learning curves and be more productive with Amazon Q Developer and Kiro. I got a chance to discuss with a couple of AWS Community Builders and community developers, who shared how Amazon Q Developer actually addressed their challenges on building applications, with several highlighting significant productivity improvements and smoother learning curves in their cloud development journeys.

As I head back to Singapore, I’m carrying with me not just memories of delicious cà phê sữa đá (iced milk coffee), but also fresh perspectives and inspirations from this vibrant community of cloud innovators.

Introducing Kiro
One of the highlights from last week was definitely Kiro, an AI IDE that helps you deliver from concept to production through a simplified developer experience for working with AI agents. Kiro goes beyond “vibe coding” with features like specs and hooks that help get prototypes into production systems with proper planning and clarity.

Join the waitlist to get notified when it becomes available.

Last week’s AWS Launches
In other news, last week we had AWS Summit in New York, where we released several services. Here are some launches that caught my attention:

Console to IDE Integration

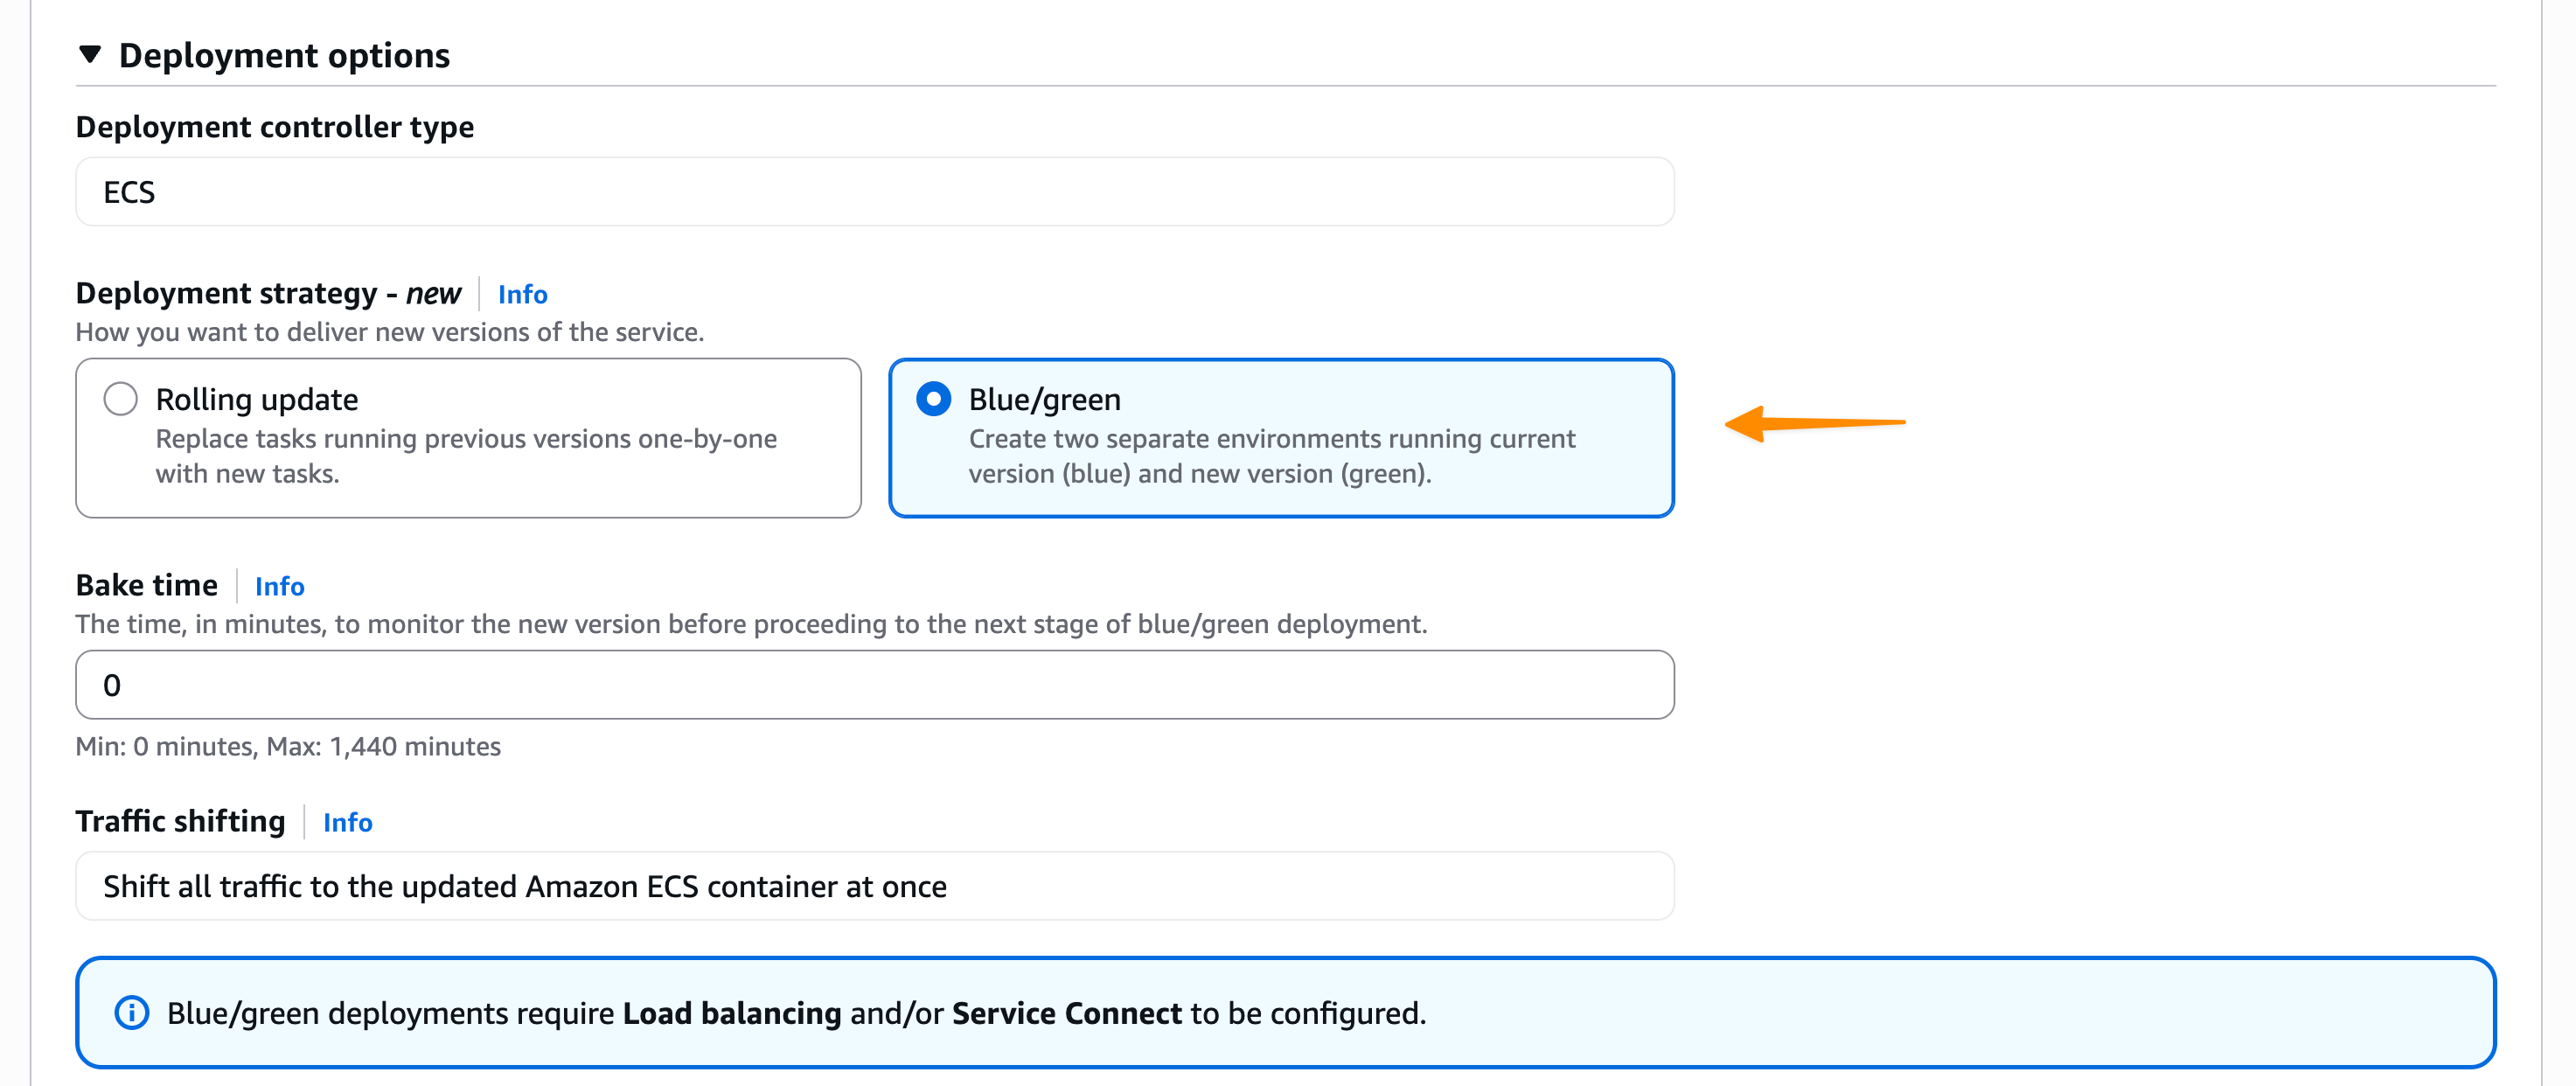
ECS Blue-Green Deployments

AWS Free Tier Enhanced Benefits

  • Monitor and debug event-driven applications with new Amazon EventBridge logging — Amazon EventBridge now provides enhanced logging capabilities that offer comprehensive event lifecycle tracking with detailed information about successes, failures, and status codes. This new observability feature addresses microservices and event-driven architecture monitoring challenges by providing visibility into the complete event journey.

EventBridge Enhanced Logging

S3 Vectors Overview

  • Amazon EKS enables ultra-scale AI/ML workloads with support for 100k nodes per cluster — Amazon EKS now supports up to 100,000 worker nodes in a single cluster, enabling customers to scale up to 1.6 million AWS Trainium accelerators or 800K NVIDIA GPUs. This industry-leading scale empowers customers to train trillion-parameter models and advance AGI development while maintaining Kubernetes conformance and familiar developer experience.

EKS Ultra-Scale Performance Improvements

From AWS Builder Center
In case you missed it, we just launched AWS Builder Center and integrated community.aws. Here are my top picks from the posts:

Upcoming AWS events
Check your calendars and sign up for upcoming AWS and AWS Community events:

  • AWS re:Invent – Register now to get a head start on choosing your best learning path, booking travel and accommodations, and bringing your team to learn, connect, and have fun. If you’re an early-career professional, you can apply to the All Builders Welcome Grant program, which is designed to remove financial barriers and create diverse pathways into cloud technology.
  • AWS Builders Online Series – If you’re based in one of the Asia Pacific time zones, join and learn fundamental AWS concepts, architectural best practices, and hands-on demonstrations to help you build, migrate, and deploy your workloads on AWS.
  • AWS Summits — Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Taipei (July 29), Mexico City (August 6), and Jakarta (June 26–27).
  • AWS Community Days — Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Singapore (August 2), Australia (August 15), Adria (September 5), Baltic (September 10), and Aotearoa (September 18).

You can browse all upcoming AWS led in-person and virtual developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Donnie

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!


Join Builder ID: Get started with your AWS Builder journey at builder.aws.com

[$] When free-software communities unite for privacy

Post Syndicated from jzb original https://lwn.net/Articles/1029769/

At DebConf25 in Brest,
France, the
talk
“When Free Software Communities Unite: Tails, Tor, and the
Fight for Privacy” was delivered by a man who introduced himself only
as intrigeri. He delivered an overview of the Tor Project, its mission, and
the projects under the umbrella. He also spoke about how the
organization depends on Debian, and plans for the software it
delivers.

Security updates for Monday

Post Syndicated from jake original https://lwn.net/Articles/1030774/

Security updates have been issued by AlmaLinux (java-1.8.0-openjdk), Debian (angular.js and batik), Fedora (chromium, pypy, screen, unbound, wine, and wine-mono), Mageia (djvulibre, quictls, and redis), Red Hat (avahi, gnome-remote-desktop, java-1.8.0-openjdk, java-11-openjdk with Extended Lifecycle Support, java-21-openjdk, kernel, kernel-rt, python-setuptools, redis, and valkey), SUSE (chromedriver, coreutils, cosign, docker, FastCGI, ffmpeg-4, fractal, gimp, glib2, ImageMagick, iputils, java-17-openjdk, java-24-openjdk, jq, kubelogin, kubernetes1.23, kubernetes1.24, kubernetes1.26, python-requests, python3, rmt-server, rustup, and thunderbird), and Ubuntu (apache2).

Streamline DevOps troubleshooting: Integrate CloudWatch investigations with Slack

Post Syndicated from Paige Broderick original https://aws.amazon.com/blogs/devops/streamline-devops-troubleshooting-integrate-cloudwatch-investigations-with-slack/

Infrastructure alerts pose a challenge for DevOps teams, particularly when they occur outside of regular business hours. The complexity isn’t merely in receiving notifications, it lies in rapidly assessing their severity and determining the root cause. This challenge is compounded when upstream service disruptions cascade into multiple downstream alerts, creating a confusion of notifications that mask the true source of the problem. DevOps teams find themselves working backwards through a complex web of interconnected services, unsure whether to start investigating at the application, network, or infrastructure level.

To reduce resolution time and alert root cause analysis, AWS introduced CloudWatch Investigations, a generative AI-powered capability within Amazon CloudWatch. Powered by Amazon Q Developer, a generative AI–powered assistant for software development, CloudWatch investigations analyzes multiple metrics, logs, and deployment events to provide suggestions for remediation and root-cause analyses, reducing alarm resolution time. A key advantage of this feature is the ability to integrate these findings directly into Microsoft Teams and Slack, making sure developers and stakeholders receive immediate alerts when issues arise. This centralized collaboration approach enables teams to work together efficiently, reducing duplicate efforts and facilitating consistent problem-solving across the organization.

In this blog post, we will walk through how to integrate CloudWatch Investigations with Slack channels and demonstrate how to interact with investigations in Slack.

Overview of the solution

CloudWatch Investigations can be started in multiple ways, like from existing Amazon CloudWatch log insights, metrics, or alarms. To demonstrate CloudWatch Investigations functionalities, we will use CloudWatch alarms in a sample web application available in the aws-samples GitHub repository. Steps on how to deploy this web app in your AWS environment, via a CloudFormation template, can be found here. You can learn more about the architecture of the resources deployed in the AWS One Observability workshop. If you choose to deploy the sample web application, you will be responsible for all service charges associated with the CloudFormation template deployment. Alternatively, you can use existing CloudWatch alarms in your environment. Examples of common Amazon CloudWatch alarms include: MemoryUtilization, CPUUtiliziation, 5xxErrors and 4xxError. A full list of available alarms can be found here.

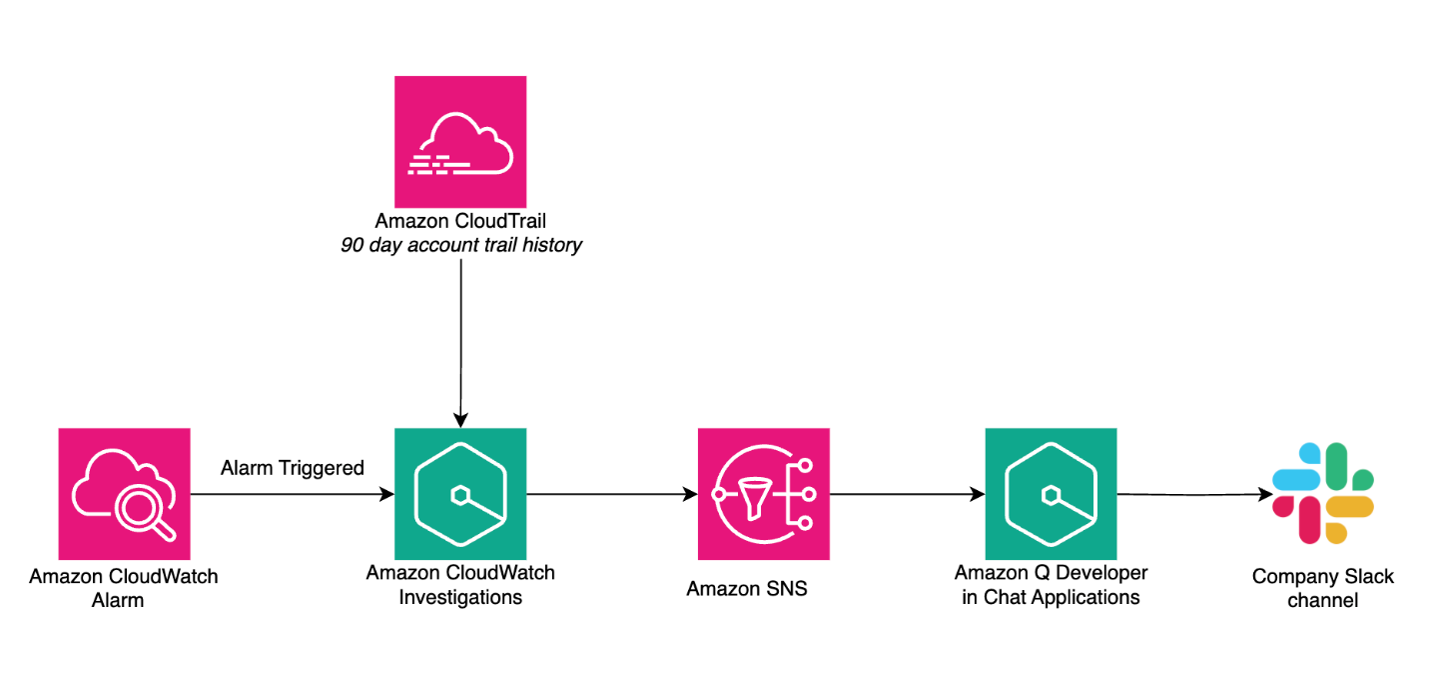
For this blog, we will utilize a pre-configured alarm to monitor when one of the website services, backed by an Application Load Balancer, experiences abnormal response times. When the alarm triggers, CloudWatch Investigations automatically initiates an investigation, analyzing both the current alarm state and 90 days of CloudTrail event history to generate hypotheses and determine potential root causes. The investigation insights are published to a Slack channel via Amazon Q Developer in Chat Applications and Amazon Simple Notification Service (SNS).

Figure 1. Architecture diagram of the services involved in the investigation integration in Slack

Prerequisites

  1. Launch the Amazon CloudFormation template associated with the One Observability lab outlined in the AWS Samples GitHub.
  2. Set up a Standard Amazon SNS topic by following the instructions outlined here. To enable CloudWatch investigations to send notifications to Slack, you must add an access policy to the Amazon SNS topic, an example can be found here.
  3. When the topic configuration is complete, navigate to Amazon Q Developer in Chat Applications (formerly AWS Chatbot) to configure the integration between Amazon Q and Slack by following the instructions outlined here. To allow channel members to interact with the investigation in Slack, add the following permission templates to the Channel role settings: Notification Permissions, Amazon Q Permissions, and Amazon Q Operations assistant permissions. More details on these permissions can be located here.

Setting up CloudWatch Investigations

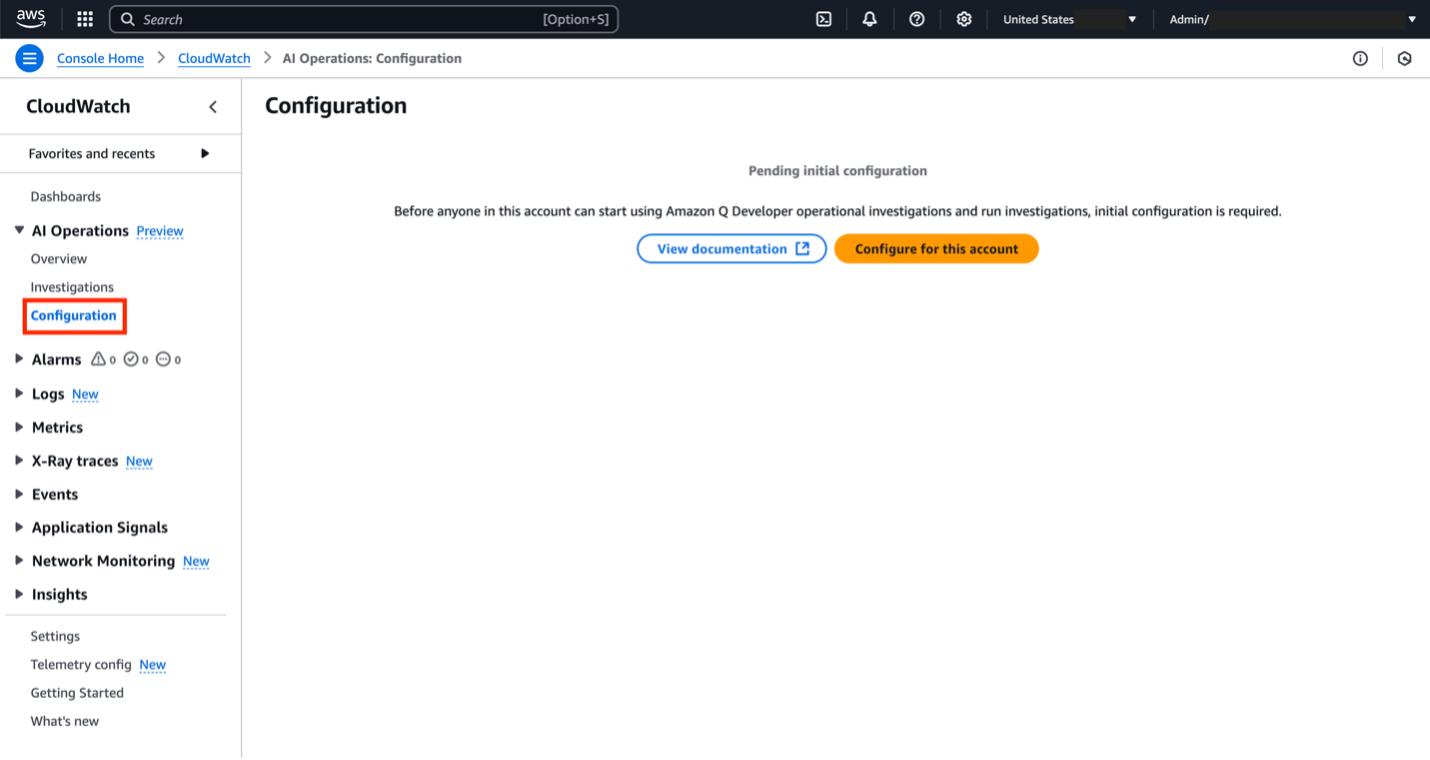
To get started, navigate to the Amazon CloudWatch console. Choose AI Operations and then Configuration.

Figure 2. Configure for this account button within the AWS Console

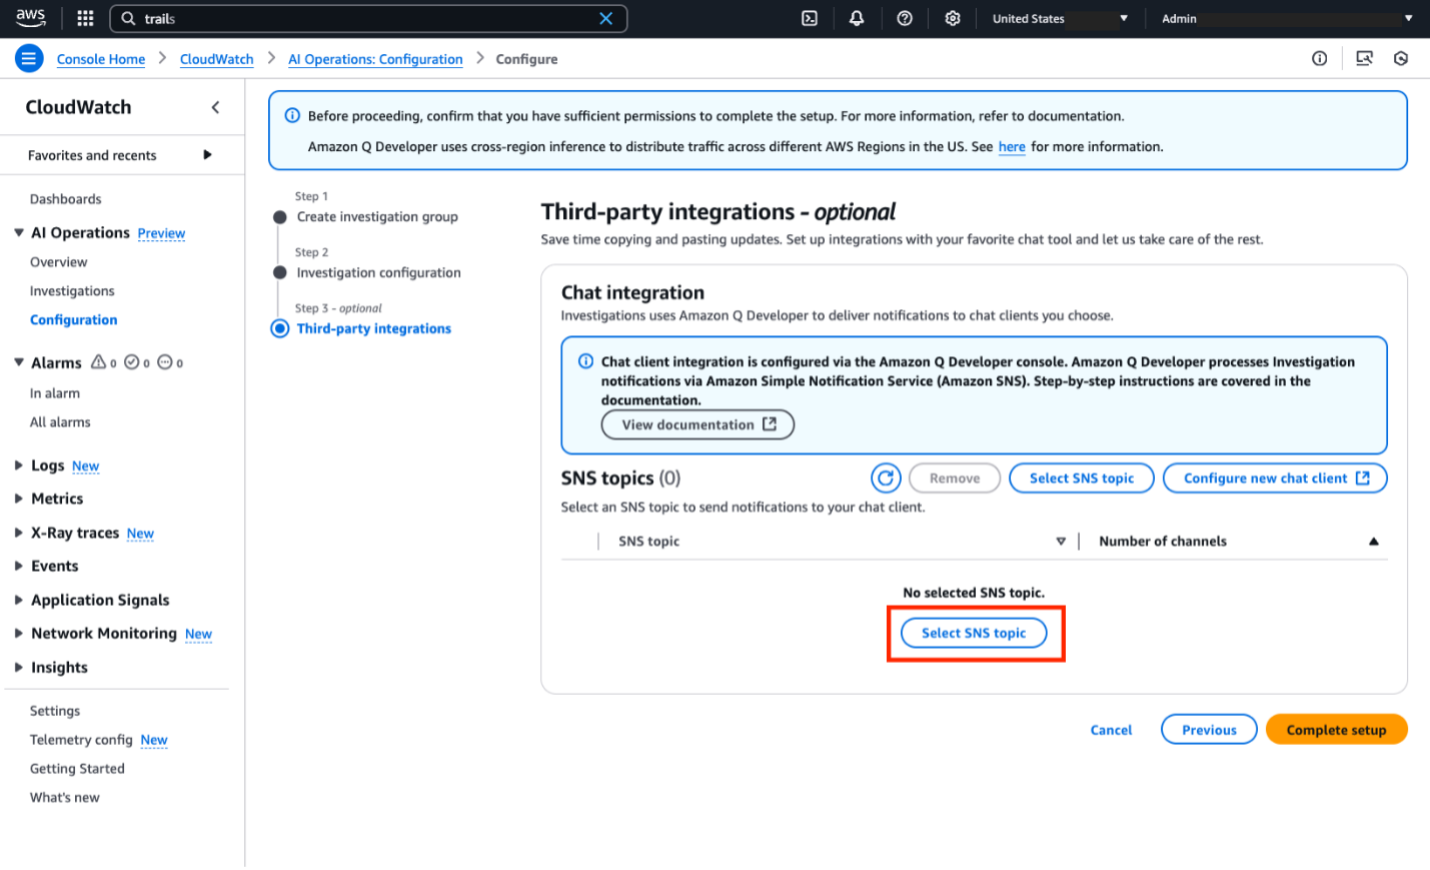
Before we can set up an investigation, we need to create an investigation group. This is an organizational structure to manage common properties of the investigation like retention requirements, encryption, access permissions and the SNS topic linked. Click Configure for this account and follow the prompts in the console to set up the investigation group. Detailed explanations for each prompt are located in the documentation here. For this demo, we left the default options for steps 1 and 2 of the prompts. In step 3, please select the existing SNS topic created in the prerequisites section.

Figure 3. Select SNS topic for Q Developer Operational Insights

For the investigation trigger, we will use an existing alarm created by the CloudFormation deployment mentioned at the beginning of this blog. The sample alarm is named:

ApplicationInsights/Services/AWS/ApplicationELB/TargetResponseTime/app/Servic-lista-... 

and it goes into ALARM state when one of the website services, backed by an Application Load Balancer, experiences abnormal response times.

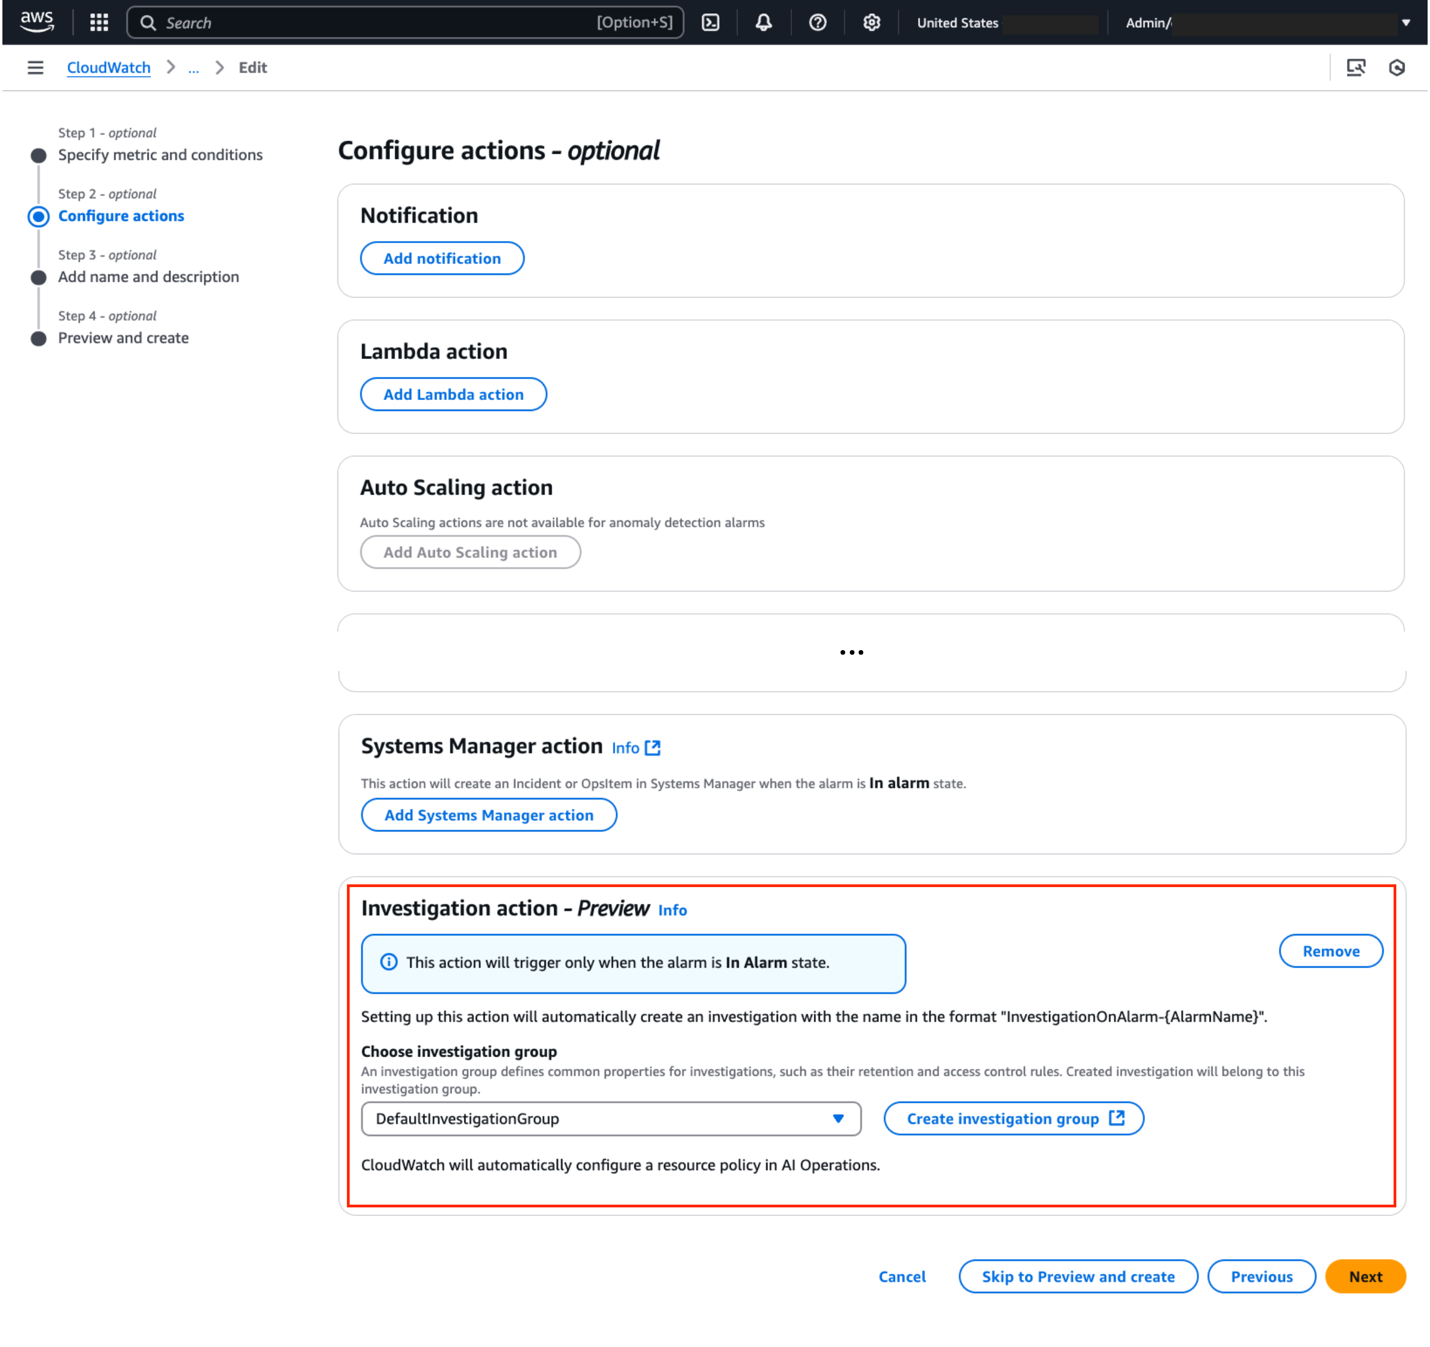
To configure this alarm to automatically start an investigation when it goes into an ALARM state:

  1. In the CloudWatch console, choose Alarms, All alarms
  2. Search for the alarm name and click on it
  3. Choose Actions, Edit
  4. Choose Next once to skip the metrics and conditions section
  5. Choose Add investigation action and then select your investigation group as outlined in figure 4
  6. Choose Skip to Preview and create, then choose Update alarm

Figure 4. Configure alarm to automatically start investigations

Testing the solution

At this point, we are ready to test the solution. To simulate a website traffic overload and trigger the alarm, we are going to use Amazon ECS tasks deployed as part of the sample web application. Open up CloudShell and run the following command:

PETLISTADOPTIONS_CLUSTER=$(aws ecs list-clusters | jq '.clusterArns[]|select(contains("PetList"))' -r)

TRAFFICGENERATOR_SERVICE=$(aws ecs list-services --cluster $PETLISTADOPTIONS_CLUSTER | jq '.serviceArns[]|select(contains("trafficgenerator"))' -r)

aws ecs update-service --cluster $PETLISTADOPTIONS_CLUSTER --service $TRAFFICGENERATOR_SERVICE --desired-count 5

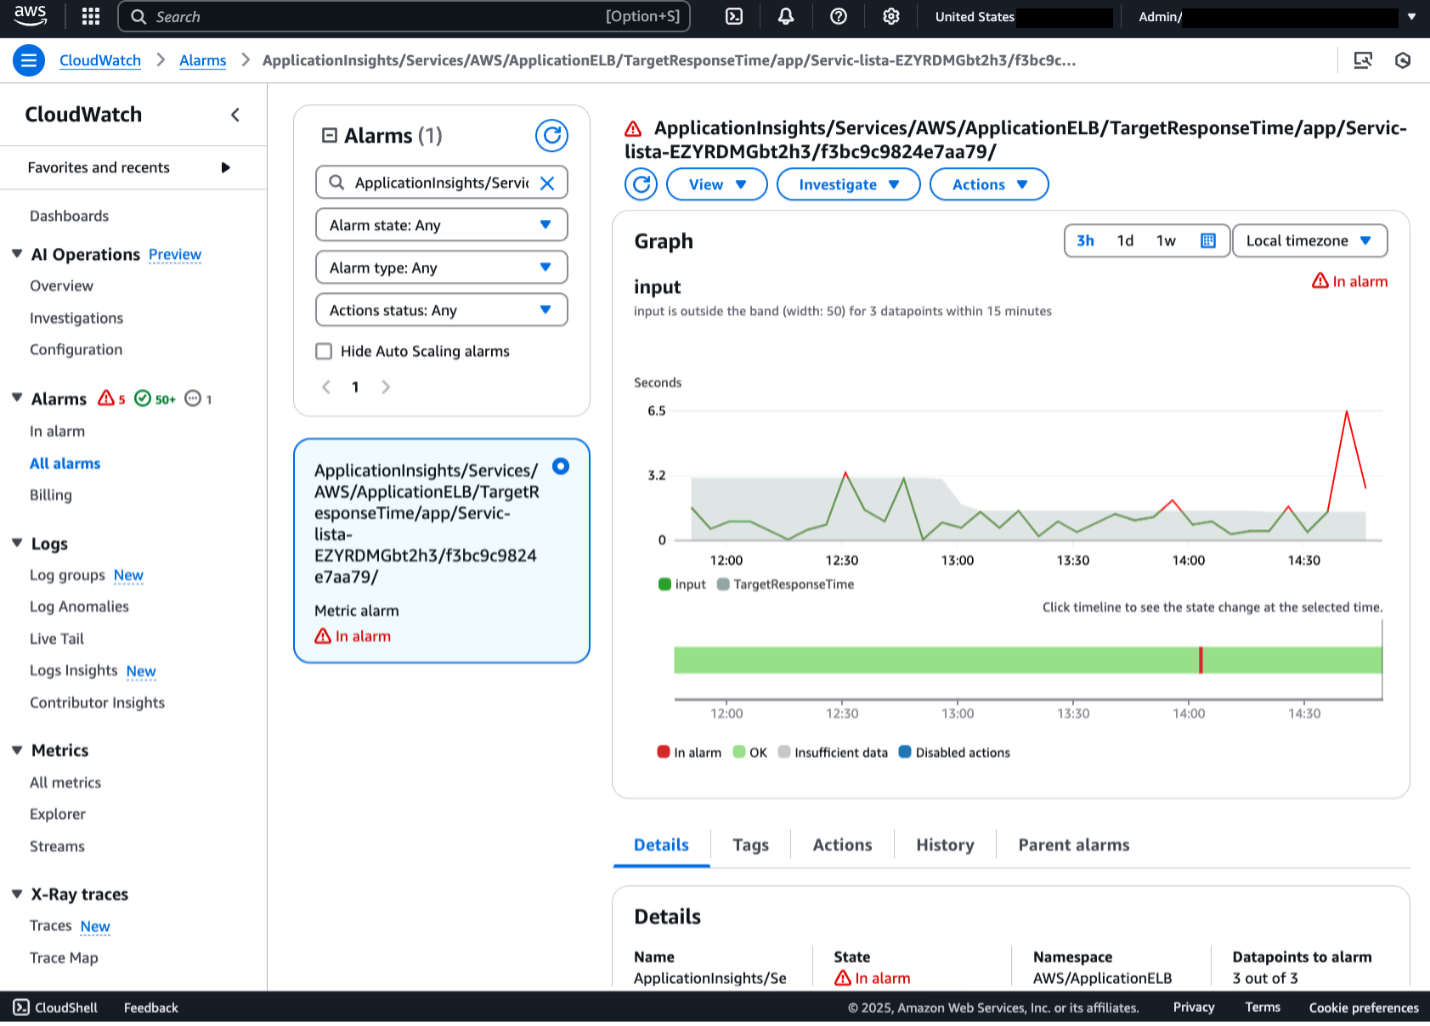
The command will launch 5 instances of the Amazon ECS traffic generator container task. Once the tasks are running (after about 5 minutes), the ALB will become overloaded with requests, forcing the alarm into ALARM state as shown below. You should also see a new investigation created.

Figure 5. CloudWatch Alarm in ALARM state

Interacting with the investigation via Slack

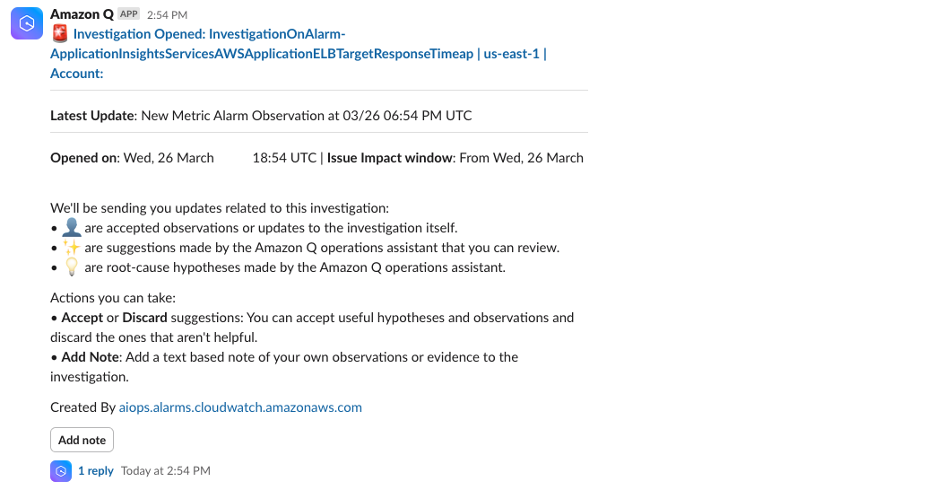
Once the alarm is triggered, an investigation is initiated. Since we associated the investigation with an Amazon SNS topic and subscribed our Slack client to it, we can see a message in our Slack channel from Amazon Q as seen in figure 6.

Figure 6. Slack notification for open investigation

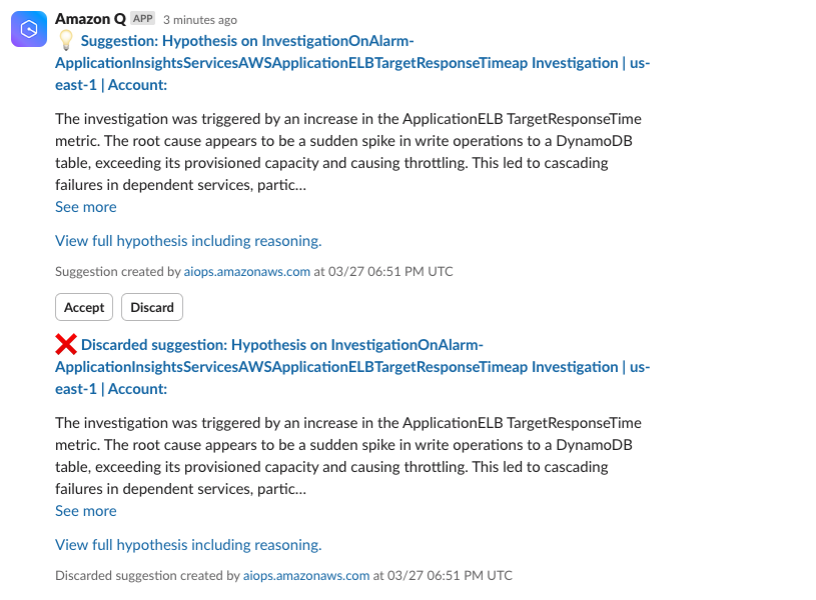
Within Slack, channel members can accept useful hypotheses and discard unhelpful ones by clicking on the Accept or Discard button. They can also add text-based notes of observations or evidence to the investigation by clicking on the Add Note button. Amazon Q will respond to messages within the same thread as the original investigation message. Channel members will be able to track who has accepted or discarded messages, as well as notes made about the investigation. This emphasizes the power of Slack integration, as teams can collaborate on the investigation and track who is actively working on it. It is important to note that CloudWatch Investigations uses Generative AI and may provide suggestions different from those below based on your specific account environment.

Figure 7. Accept or discard investigation suggestions from Slack

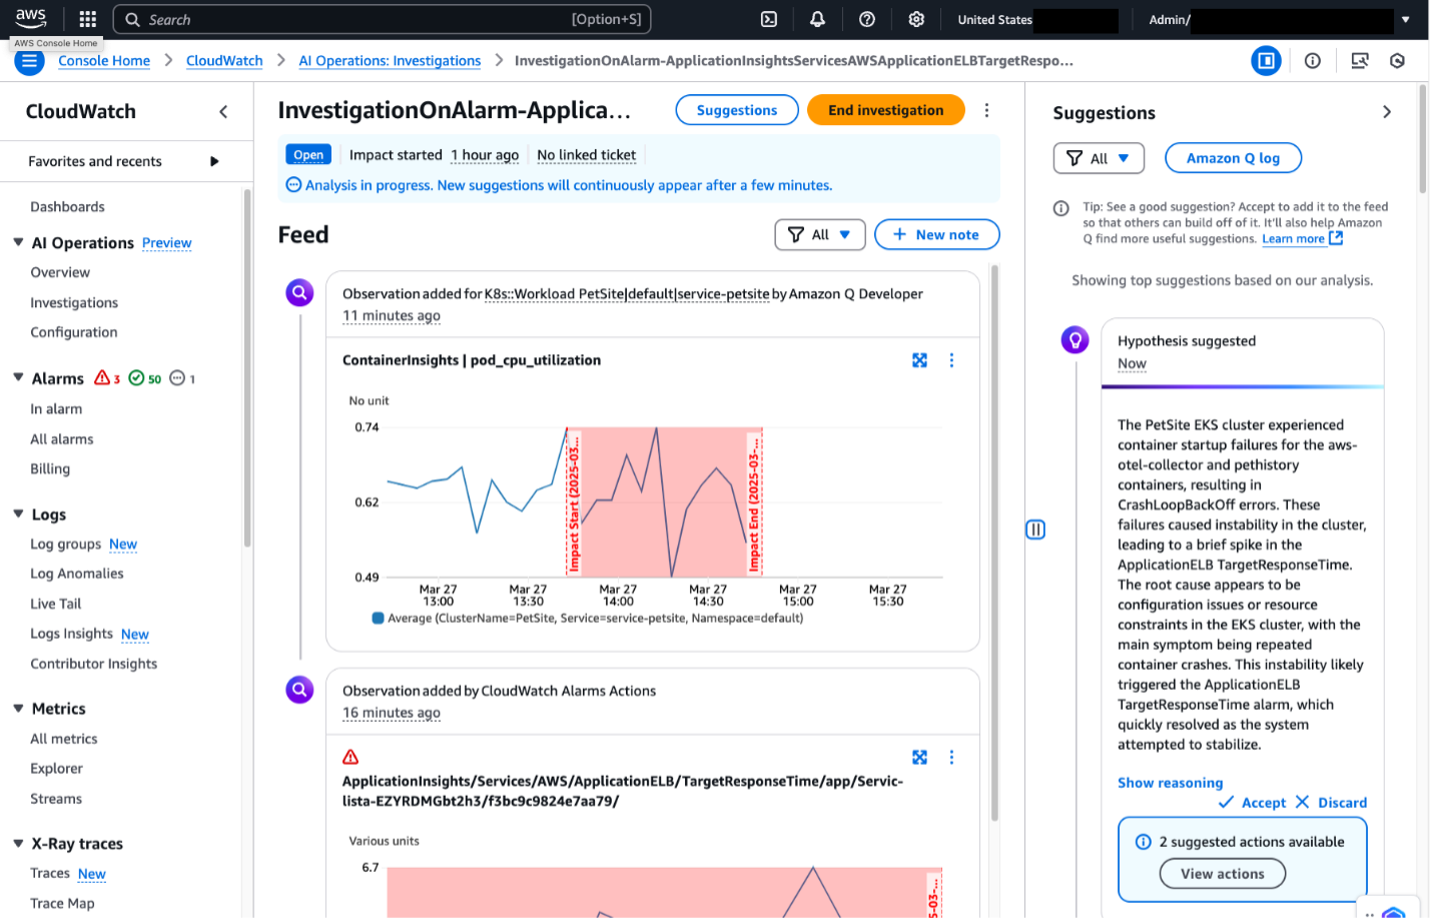
When integrated with Slack, CloudWatch Investigations can provide suggestions and root-cause hypotheses. Channel members with appropriate permissions can access metrics, charts, and additional information related to the investigation by clicking the blue header at the top of the investigation message. This link will direct users to the CloudWatch Investigations feed in the AWS console as shown below in figure 8.

Figure 8. CloudWatch Investigations in CloudWatch console.

Integrating CloudWatch Investigations with Slack or Teams channels improves developers’ visibility of arising issues and provides targeted recommendations to reduce alarm resolution time. The Accept and Discard buttons make it straightforward to track who is actively working on an investigation, fostering a culture of collaboration. The best part? The integration is quick to set up, especially with existing alarms.

Clean Up

If you launched the CloudFormation template mentioned at the beginning of this blog, the services will continue to run unless you delete them. To make sure that you are not charged for use of the resources after the demo, please follow the below steps to delete the resources created as part of the steps performed on this blog.

  1. Remove the Amazon Q in Chat Applications Slack integration by clicking on Remove Workspace Integration and policy as explained here.
  2. Delete Amazon SNS topic and subscription as explained here.
  3. Remove the CloudWatch Investigations as explained here.
  4. Delete the images under the Amazon ECR repository named cdk-…-container-assets… as explained here.
  5. Open the CloudShell console or AWS CLI and execute the two commands below:
curl https://raw.githubusercontent.com/aws-samples/one-observability-demo/main/PetAdoptions/cdk/pet_stack/resources/destroy_stack.sh | bash

aws cloudformation delete-stack –stack-name CDKToolkit

After executing the above command, the resources of the demo should be destroyed. Look at the CloudFormation console in case of potential errors.

Conclusion

The new CloudWatch Investigations feature reduces alarm resolution time for development teams by providing actionable insights and recommendations. It is straightforward to connect investigations to a team’s primary form of communication, such as Teams or Slack, to improve notification awareness and interaction. To learn more about the capabilities of CloudWatch Investigations check out the feature announcement and documentation.

Happy investigating!

Another Supply Chain Vulnerability

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/07/another-supply-chain-vulnerability.html

ProPublica is reporting:

Microsoft is using engineers in China to help maintain the Defense Department’s computer systems—with minimal supervision by U.S. personnel—leaving some of the nation’s most sensitive data vulnerable to hacking from its leading cyber adversary, a ProPublica investigation has found.

The arrangement, which was critical to Microsoft winning the federal government’s cloud computing business a decade ago, relies on U.S. citizens with security clearances to oversee the work and serve as a barrier against espionage and sabotage.

But these workers, known as “digital escorts,” often lack the technical expertise to police foreign engineers with far more advanced skills, ProPublica found. Some are former military personnel with little coding experience who are paid barely more than minimum wage for the work.

This sounds bad, but it’s the way the digital world works. Everything we do is international, deeply international. Making anything US-only is hard, and often infeasible.

EDITED TO ADD: Microsoft has stopped the practice.

Площадки за дронове и медицински хеликоптери

Post Syndicated from Боян Юруков original https://yurukov.net/blog/2025/dronove-i-helikopteri/

Сагата с медицинските хеликоптери върви от много години. В последните две има сякаш някакъв напредък към устойчив модел на работа. Правителството се похвали дори с десетина хеликоптерни площадки в болници и ключови места. Те са детайл, който остана на заден план покрай несигурността дали хеликоптерите въобще са изрядни или безопасни да летят, дали пилотите са обучени и прочие.

Покрай разкритието, че комплекс Диана в София е „отцепено“ за дронове от НСО само защото Бойко Борисов рита там мач преди да вечеря в „офиса“ на Сталийски в ресторант 101, се поинтересувах къде има такива зони и как се създават. Разбира се, въпреки че след скандала зоната пазеща мачлетата на Борисов беше махната, миналата година ми беше отказана информация какви са били точно аргументите на НСО. Причината беше, че НСО не давали. В действително премахването на зоната предполага отпаднала необходимост, което от своя страна означава, че рискът за това не съществува и причините не следва да са засекретени. Добър пример е за това как се укрива неправомерни действия чрез засекретяване. Често такива се укриват допълнително чрез блокиране на изслушвания в НС.

По същото време – април 2024-та – попитах ГД ГВА защо няма обозначени ограничения за използване на дронове покрай обявените тогава четири площадки в София. Това е важно, защото дроновете са особено опасни за хеликоптерите, а в градска среда се използват често. Бяха тъкмо пуснати или в процес на сертифициране и вече имаше полети, включително на пациенти. Отговориха ми, че процесът е сложен и са на финалната права да добавят такива ограничения.

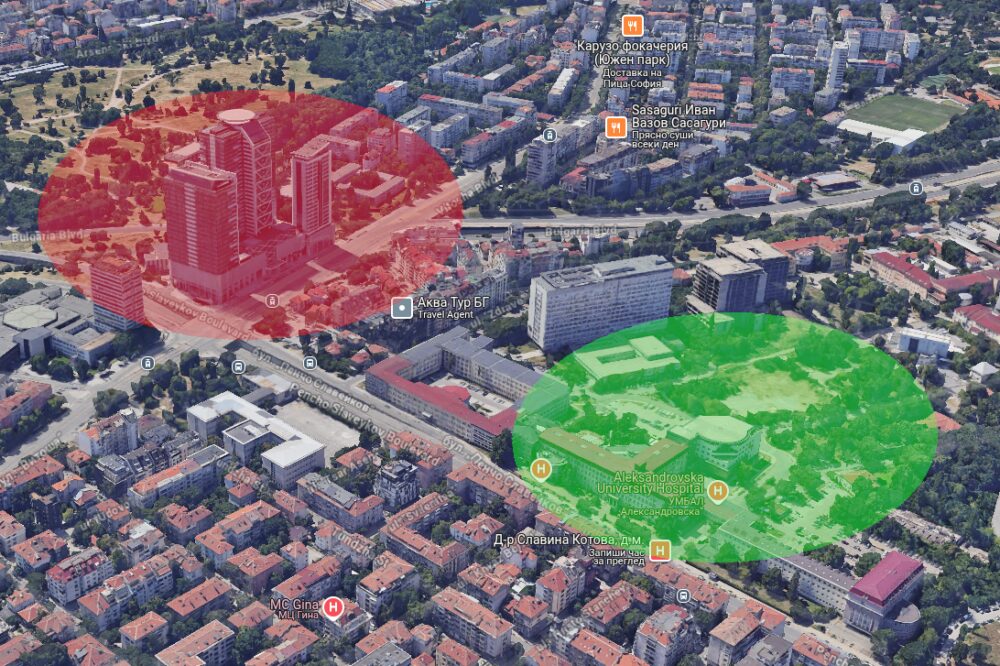
Интересното в случая е, че в някои случаи има подобни площадки, които са защитени. Пример са кулите до НДК, където явно навремето доста бързо са ограничили дроновете. В същото време площадката в седство в Св. Екатерина, която отдавна съществува, все още няма такова ограничение. Това виждаме на интерактивната карта на дирекцията. Те публикуват ограниченията в единен формат, който е неразделна част от заповедите.

Наскоро ги попитах отново защо хеликоптерните площадки не са покрити с ограничения. Повече от година по-късно не само няма промяна в картата и документацията им, но и вече площадките са 10 (изключвайки спряната в Русе). Виждаме ги в списък на страницата на дирекцията.

  • БВЛ „Уни Хоспитал“
  • БВЛ „СВЕТА АННА“
  • БВЛ „ЛОЗЕНЕЦ“
  • БВЛ „СВЕТА ЕКАТЕРИНА“
  • БВЛ „МОБАЛ Д-р Стефан Черкезов – В. Търново“
  • БВЛ „ТУНЕЛ ЖЕЛЕЗНИЦА“
  • БВЛ „Д-р Стамен Илиев“
  • БВЛ „УМБАЛ СВЕТИ ГЕОРГИ“
  • БВЛ „МБАЛ – ШУМЕН“
  • БВЛ МБАЛ „Д-Р Атанас Дафовски“

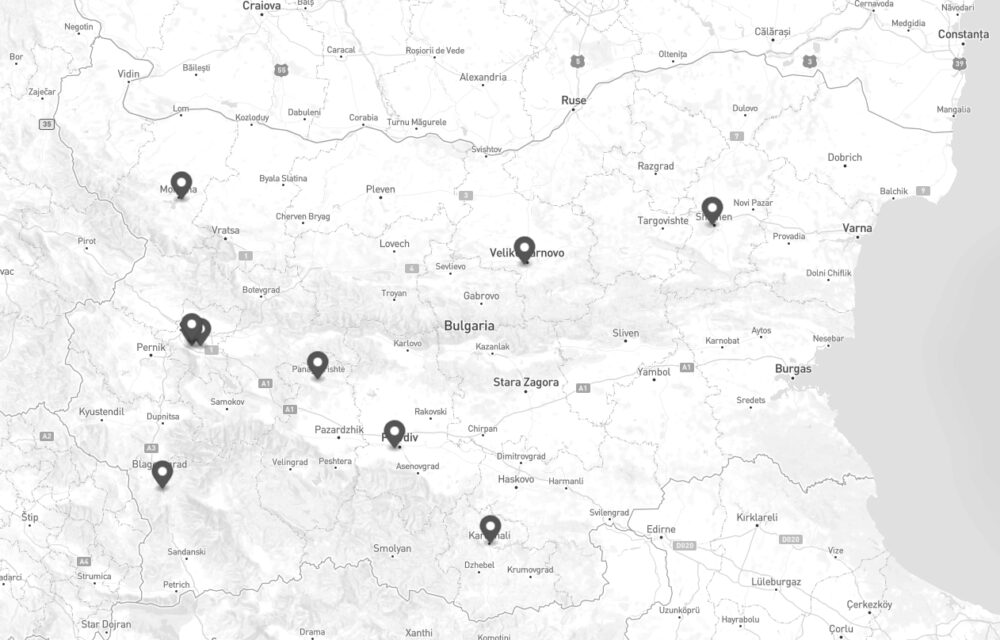
Отбелязал съм ги на тази карта. Три са в София. Няма такива в Стара Загора, Бургас или Варна.

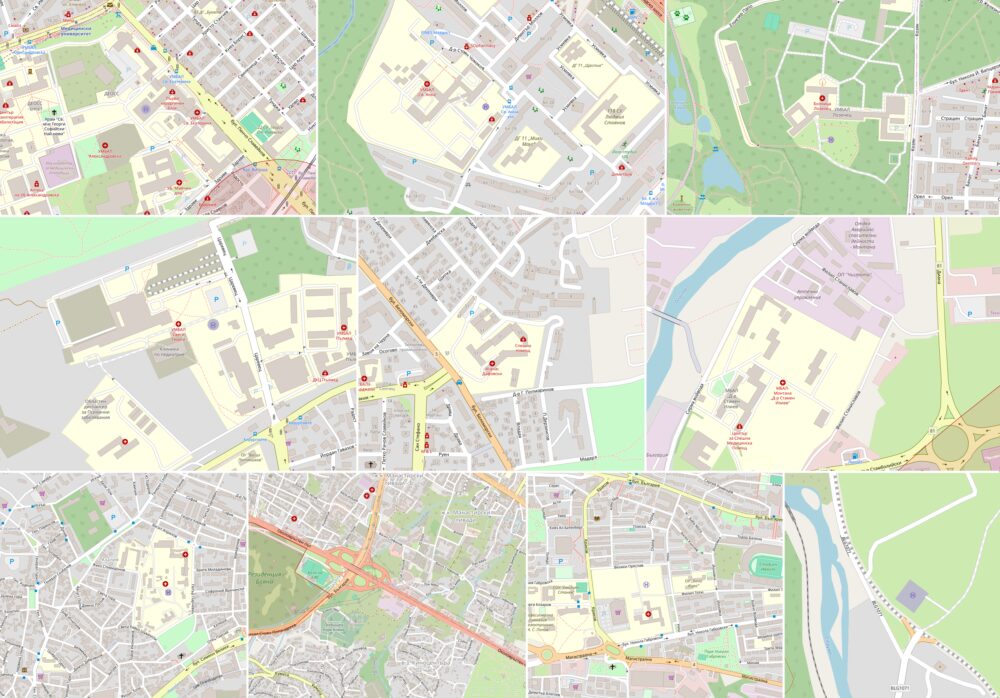
Тук виждате снимки на интерактивната карта на дирекцията към началото на юли. Виждате, че няма отбелязани ограничения. Виждат се маркирани в близост ограничения на други обекти, включително примера, с който започнах.

Този път ми отговориха, че процесът е много сложен и все още върви година по-късно, независимо, че ми бяха казали, че са на финалната права за първите площадки. Посочиха обаче, че нямало проблем, защото нямало такова изискване за пускане на площадките в експлоатация.

Поради технологични особености и ограничения, процесът по публикуване на информация за географските зони на БЛС изисква време. Независимо от това, действащите регулаторни механизми за експлоатация на БЛС осигуряват необходимото ниво на авиационна безопасност при текущото използване на болничните вертолетни площадки.

При експлоатация на БЛС в неограничена категория, определена в чл. 4 от Регламент за изпълнение (ЕС) 2019/947, дистанционно управляващият пилот поддържа визуален контакт с БЛС, което му позволява прецизен контрол върху траекторията на полета и предотвратяване на сблъсъци с други въздухоплавателни средства, хора или препятствия. При експлоатация в специфичната категория, определена в чл. 5 от Регламент за изпълнение (ЕС) 2019/947, операторът на БЛС следва процедура за издаване на разрешение, която включва предварителна оценка на риска и определяне на подходящи мерки за намаляване и управление на риска, съгласувани с ГД ГВА.

Следва да се отбележи, че към настоящия момент няма действащи нормативни изисквания, които да обвързват въвеждането в експлоатация на болнични вертолетни летища с предварително установяване на географски зони на БЛС около тях.

Отговорното лице за обработване на информация за географските зони е началник отдел “Безпилотни летателни системи, международна дейност и иновации”, дирекция „Авиационна безопасност“ в ГД ГВА.

Може би се питате защо едни кръгчета на карта на сайт на дирекция имат значение когато всеки може да вдигне дрон. Би следвало да се използва здрав разум в такива случаи и да не се излагат на риск медицинските хеликоптери. Още повече, че вече има ограничения покрай летища и пак биват затваряни защото дронове се забелязват в близост. При липса на такива ограничения обаче съвсем няма причина да се санкционират неразумните. Такива би били например медиите ни гонещи кадри на кръв за новинарските си емисии или други търсачи на сензации. Дори да не се стигне до инцидент, забелязването на дрон може да забави кацане или излитане, което да изгуби ценни минути. Търсенето на отговорност дори при кадърен прокурор, би била трудно затруднена. Отделно по-тежките и сложни машини имат изисквания автоматично да избягват такива ограничителни зони, което прави този списък важен.

За сега според дирекцията проблем няма, но се работи все още по въвеждането на такива ограничения. Т.е. решаването на проблема. Ще питам след година отново или когато някой забие дрон във витлата – което дойде по-рано.

The post Площадки за дронове и медицински хеликоптери first appeared on Блогът на Юруков.

The collective thoughts of the interwebz