Two-thirds of enterprise leaders see significant potential in integrating AI models with their proprietary data. Yet only 22% feel confident their current IT infrastructure could actually support new AI applications. That gap—between ambition and capability—is where most AI investments stall, budgets balloon, and promising projects quietly get shelved.
The problem isn’t the models, the change management, or even the cost. It’s the underlying data foundation.
The conversation that never happens
The problem is not that either conversation is wrong. It is that they happen separately.
Most organizations run two parallel conversations about AI, and they rarely meet in the same room until a deployment runs into trouble.
The first happens at the strategy level: executives identify use cases, project ROI, approve budgets, and set timelines.
AI is treated as a technology question with business outcomes.
The second happens further down the stack: infrastructure teams make decisions about where data lives, how it moves, and who can access it.
Storage is treated as a cost question, divorced from strategy.
This separation is intuitive. Different people work on it. Different timelines apply. Different success metrics matter. But the separation is a liability disguised as organizational structure.
Two-thirds of executives leading infrastructure efforts say they are excluded from key AI decision-making conversations. Every model selected, application built, and workflow redesigned depends on the same thing: a data foundation that either supports the strategy or constrains it.
That foundation has to be built alongside the strategy, not bolted on as an afterthought.
The cost of misalignment
There are consequences to this misalignment. When data infrastructure decisions get made separately from AI strategy, the result is predictable: AI teams discover too late that the data they need is fragmented, inaccessible, or poorly governed. Infrastructure teams optimize for cost without knowing what future AI workloads will require. Business leaders fund use cases without validating whether the data foundation can support them.
And more specifically, a company building an internal tool to surface insights from customer support transcripts needs audio and text data organized, labeled, and retrievable before the tool can work. A company developing an AI-powered product for external customers needs guardrails in place for data provenance, consent, and version control before model selection matters. Both depend on data that is governed and accessible before any model enters the picture.
Yet according to Gartner’s survey of data management leaders, 63% of organizations either don’t have or aren’t sure they have the right data management practices for AI. Gartner’s projection is stark: through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data.
Each abandoned project represents sunk cost, such as engineering hours and vendor contracts.
And yet, the pattern repeats because the problem is structural. Strategy teams set direction without validating that infrastructure can support it. Infrastructure teams make decisions without understanding what the strategy actually requires.
Neither group is wrong; they’re simply operating from different information, different incentives, and different success criteria.
What changes when AI strategy becomes business strategy
When organizations treat AI strategy and data strategy as the same conversation, the outcomes shift. Three things happen:
Infrastructure decisions get made with strategic context. Where data lives, how it moves, what it costs—these have become capability questions rather than cost optimization questions. AI development depends on iteration: moving data between tools, environments, teams, and models. A storage provider that charges $90 per TB for egress can become architecturally limiting, penalizing the high-frequency data movement that accelerates AI development. When CFOs understand that the storage decision determines whether the organization can iterate quickly or iterate slowly, the conversation changes.
AI initiatives get funded with data readiness built in.BCG’s research on future-built companies found that top performers define AI programs with ambitious cost and revenue targets set at the executive level and hold teams accountable to near-term results. What they also have in common: they’ve established governance structures, inventoried their data assets, and planned infrastructure before deployment pressure arrives.
Accountability shifts. According to McKinsey’s 2025 State of AI survey, 28% of organizations using AI report that their CEO is responsible for overseeing AI governance—the policies, processes, and controls that determine how AI is developed and deployed. McKinsey’s analysis found that CEO oversight of AI governance is one of the factors most correlated with meaningful bottom-line impact from AI use. When executive leadership owns both strategy and governance, the two stay aligned.
A companion resource to help you make data decisions
AI strategy cannot succeed as a standalone initiative. It depends on the organization’s ability to make data available, portable, governed, and cost-effective at the exact moments teams need it. For leaders, that means treating infrastructure not as a downstream implementation detail, but as part of the strategy itself.
Read the ebook, Navigating Multimodal Dataset Economics, to get the guide on making decisions about the AI datasets at your organization, and how interoperable-by-design object storage is critical for multimodal AI datasets.
There’s a familiar tension in enterprise technology: buy a fully integrated platform or assemble a stack of best-of-breed components. The platform story is compelling: one vendor. One console. One contract. Everything bundled together.
The best-of-breed story is different. Best-of-breed optimizes each layer for performance, flexibility, and cost. Historically, platforms often won the narrative. But in periods of rapid change—like today’s AI era—modularity regains the advantage.
The platform gravity problem
Platforms can introduce operational gravity. When compute, storage, networking, analytics, governance, and AI tooling all live in one ecosystem, switching costs rise over time. What starts as convenience becomes constraint—and in AI, where tooling changes rapidly, that becomes expensive in both flexibility and economics. Industry leaders reflect this shift. CIOs are moving beyond a “cloud-first” mindset toward “cloud-smart” strategies and choosing the right environment for each workload instead of defaulting to one provider’s stack. This proactively avoids escalating costs and inflexible ecosystems. A recent CIO Dive trend report finds many IT leaders are gravitating toward purpose-built infrastructure optimized for specific workload demands—including AI—rather than broad commodity offerings.
Why modular infrastructure wins
AI pipelines evolve constantly: training datasets, checkpoints, GPU migrations, MLOps workflows and post-processing outputs are all subject to rapid changes to scale applications and extend model capabilities. Few organizations run all of that inside a single vendor environment or a single cloud ecosystem. Teams building differentiated systems optimize workflows and resources, not monoliths.
Modularity isn’t just about avoiding lock-in—it’s about real, measurable agility. Modular architectures allow organizations to adjust components independently as requirements change. CTOs are intentionally placing workloads where they perform best—cloud for global scale, on-prem or colocation for heavy AI training, and edge for low-latency inference—and treating each as part of a unified, purpose-driven infrastructure strategy.
This pattern holds true beyond just AI.
In cyber resilience, what matters when a ransomware event hits isn’t whether you bought every tool from one vendor; it’s the speed and predictability of recovery (which specialized, resilient storage does more to accelerate than bundled dashboards)
In cloud native application development, developers value predictable performance, clear pricing, and flexibility over being locked into a single ecosystem.
In media and entertainment, workflows often span regions, partners, and technologies—moving petabytes of creative content, generating AI media assets, and orchestrating distributed rendering jobs. A modular approach enables teams from all sides of the business (creative and technical) to optimize for performance without constraint.
These use cases share common themes: avoid lock-in, preserve optionality, control costs, and maintain performance predictability. These align with broader industry sentiment that hybrid and composable architectures deliver greater agility and resilience in the face of evolving requirements.
Depth over breadth: A focused infrastructure philosophy
When vendors expand aggressively into adjacent domains—analytics, governance, AI tooling—they risk breadth at the expense of depth. In fast-moving markets, “jack-of-all-trades” platforms often become “master-of-none.” Best-of-breed doesn’t mean disjointed; it means each layer is optimized for its purpose and integrated intelligently.
That’s the philosophy behind how we’ve evolved our own infrastructure. When Backblaze first launched our object storage service, we highlighted performance, transparency, and cost efficiency. As AI and high-throughput workloads accelerated, customers began using us as neutral infrastructure for staging, throughput, and data mobility between clouds. We leaned deeper into storage—high-throughput tiers, bandwidth guarantees, lifecycle tools—but intentionally stopped short of climbing higher up the application or analytics stack.
We draw a line at storage not because adjacent layers lack value, but because storage is foundational. AI differentiation, application logic, and workflow intelligence happen above the infrastructure layer. Customers need owned, interoperable workflows that can plug into any compute or AI platform without being co-opted by a monolithic ecosystem.
Modular infrastructure as a strategic backbone
Best-of-breed doesn’t mean fragmentation; it means focus with composability. The future of enterprise infrastructure isn’t about building the tallest platform—it’s about building the strongest foundation that supports innovation across many dimensions.
Across industries, infrastructure leaders are embracing workload placement strategies and hybrid models to optimize for cost, governance, and performance. In AI, this means hybrid cloud and on-prem strategies where appropriate; in traditional application and file storage, it means interoperable, resilient services; and in media workflows, it means performant pipelines unencumbered by monolithic stack limitations.
The companies that win in this era won’t be those who own every layer. They’ll be those who enable others to build faster, iterate often, and adapt without constraint.
AI cloud platforms have spent the last few years competing on GPU availability, interconnects, and cluster performance. That makes sense. GPUs are the engine of AI infrastructure, and demand for them has been relentless.
But a GPU can only work as fast as the data pipeline feeding it.
Think of it like a fleet of race cars. You can have the best cars on the track, the fastest pit crew, and a perfect race strategy. But if the fuel lines supplying the pit tanks can’t move gasoline fast enough, the cars are going to sit there waiting.
The cars are not the problem. The fuel supply system is.
The same thing happens in AI infrastructure. GPUs rely on high-performance flash storage when training models or running inference. But before data can be served from that flash tier, it often needs to move from durable object storage into the performance layer. If that upstream object storage layer can’t deliver data quickly and consistently, the entire pipeline slows down.
That’s why GPU availability is only half the equation. The other half is the data supply architecture that keeps those GPUs working.
The hidden bottleneck in AI infrastructure
AI workloads move a lot of data, constantly. Training datasets need to be staged and prepared so jobs can access them quickly. Model checkpoints, artifacts, embeddings, and intermediate outputs need to be written back for durability and reuse. Inference pipelines generate their own steady stream of reads and writes as models serve predictions and capture outputs.
All of that activity puts pressure on the storage and networking layers underneath the AI platform.
The bottleneck usually does not come from one obvious failure. Instead, it builds from a few things happening at once:
Data retrieval slows down under load.
Network paths become congested.
Request overhead compounds at dataset scale.
I/O behavior becomes less predictable as concurrency increases.
Individually, each of these may seem manageable. Together, they can quietly limit how efficiently AI infrastructure runs.
And the problem gets more visible as platforms scale. A handful of GPUs might be fine, while dozens or hundreds of GPUs create a very different demand profile. The upstream storage layer has to sustain much higher aggregate throughput while also absorbing frequent checkpoint and artifact writes.
Adding more GPUs increases potential compute capacity. But it also increases the rate at which data has to move.
Without enough throughput from the upstream data layer, more compute does not automatically translate into more performance.
Idle GPUs are expensive GPUs
When GPUs wait on data, the impact is both technical and financial.
First, idle GPUs waste compute capacity. GPU time is expensive, and AI workloads are designed to keep those processors busy. When the data pipeline can’t keep up, organizations end up paying for compute that is not being fully used.
Second, data delays slow development. Training runs take longer. Clusters stay reserved for more time. Teams wait longer to evaluate results. Even small drops in utilization can raise the cost of AI work because each run takes longer to finish.
Over time, that means slower iteration, delayed experiments, and longer paths to new models and features.
For AI cloud platforms, the risk is even bigger. Customers judge the platform by outcomes: how quickly jobs start, how consistently workloads run, and whether performance scales as expected. If jobs take longer than expected or results vary from run to run, customers may assume the GPUs are the issue.
But the real problem may be that the data pipeline can’t deliver data fast enough.
AI changes what object storage needs to do
Object storage has traditionally been evaluated around durability, scalability, cost, and general-purpose cloud performance. Those still matter, and AI infrastructure adds a new requirement: sustained data movement.
AI workloads require an object storage layer that can continuously supply downstream performance tiers under real-world load.
That means object storage needs to:
Sustain high aggregate throughput, not just short bursts.
Deliver predictable performance under continuous data movement.
Absorb large checkpoint and artifact writes.
Quickly rehydrate data when needed.
Many traditional object storage architectures were not built for this kind of steady, high-volume supply model. They can perform well for archival workloads, backups, and general-purpose applications, but AI introduces sustained pressure that exposes architectural limits.
The result is rarely a dramatic failure. More often, it looks like variability. Performance fluctuates under load. Scaling becomes harder to predict. GPU clusters wait on data more often than they should.
That variability becomes a competitive problem.
For AI clouds, storage is now part of the product experience
GPU availability is becoming table stakes. What separates platforms is not just how many GPUs they advertise, but how reliably those GPUs translate into real-world AI performance and productivity.
We said that customers care about outcomes. They want models to train faster. They want workloads to stay stable as they scale. They want infrastructure that helps them iterate quickly instead of introducing another bottleneck.
That means the upstream data layer has become performance infrastructure.
The storage layer also shapes the customer experience. If storage feels disconnected, complicated, or bolted on, customers notice. If it is native, branded, performant, and easy to consume, it strengthens the platform.
That is where B2 Neo comes in.
B2 Neo: Storage built to keep AI workloads moving
Backblaze B2 Neo gives platforms a high-throughput, white-label object storage backbone designed to support AI workloads at production scale.
It is S3-compatible, engineered for sustained throughput, and built to supply high-performance flash tiers without forcing providers to build and operate complex storage infrastructure in-house.
With B2 Neo, AI cloud platforms can offer object storage as a native extension of their own platform, including branded endpoints, partner-controlled pricing, and API-driven provisioning. That gives providers a new branded revenue stream while keeping the customer experience centered on their own platform.
B2 Neo also supports private connectivity options, helping create dedicated data paths that reduce shared network contention and improve predictability for demanding workloads. Backblaze has positioned the platform for high-throughput use cases, including up to 1Tbps aggregate throughput for AI and media workloads.
For platforms, that means storage becomes less of a build-vs-buy distraction and more of a platform advantage.
What AI clouds gain
When the data supply layer can keep up, GPU infrastructure becomes more effective.
Neocloud platforms can improve GPU utilization by reducing the time clusters spend waiting on data. AI teams can iterate faster because training runs and experiments move through the pipeline more efficiently. Platform performance becomes more predictable as datasets grow and clusters scale.
And operationally, neoclouds avoid the burden of building, scaling, and maintaining a large object storage system themselves.
That matters because every engineering cycle spent building commodity infrastructure is a cycle not spent improving the core compute platform, customer experience, orchestration layer, or AI-specific tooling.
The bottom line
AI clouds are winning because they give builders access to the compute resources they need. But compute alone is not enough.
A GPU cluster is only as useful as the data pipeline that keeps it fed.
As AI workloads scale, the storage layer becomes part of the performance story. The neoclouds that solve the data throughput problem will be better positioned to deliver consistent customer outcomes, improve GPU utilization, and turn storage into a native part of the platform experience.
GPU availability is only half the equation; Backblaze delivers the other half.Interested in learning how Backblaze supports AI cloud platforms? Explore B2 Neo or reach out to start a technical and strategic conversation.
Engineering teams build internal command-line interface (CLI) tools because repetitive operational tasks such as generating reports, auditing infrastructure, and checking service health are faster and more reliable when automated behind a consistent interface. A well-built CLI replaces ad-hoc scripts with structured commands, standardized error handling, and composable workflows that any team member can run. However, building these tools follows a predictable development lifecycle. The developer sets up a package, writes commands, handles errors, and ships it, then spends the next six months as its sole maintainer. Meanwhile, requests for new commands, custom report formats, and one-off integrations pile up as other teams across the organization discover the tool is useful for their workflows too. Frameworks like Click and Typer reduce the friction, but every new command still needs to be written, tested, and deployed manually.
Tools that generate their own capabilities on demand offer a different approach. Instead of writing each command manually, users can describe what is needed in natural language, and the tool writes the code, loads it, and makes it available at runtime without requiring a restart or redeployment. This is called meta-tooling, a repeatable pattern for giving applications the ability to create their own tools dynamically. For teams that maintain growing collections of internal utilities, this eliminates the bottleneck of having a single developer write every new feature.
In this post, we will walk through one implementation of this pattern, a CLI generator called CLI Creator. CLI Creator combines three technologies into a mechanism that organizations can adapt for their own use cases:
Amazon Bedrock, a fully managed service for building generative AI applications with foundation models, with Anthropic’s Claude Opus 4.6 for AI-powered code generation.
Strands Agents SDK, an open-source Python framework for building AI agents with tool use, for dynamic tool creation, loading, and execution at runtime.
Model Context Protocol (MCP), an open standard for connecting AI applications to external data sources and tools, for automatically discovering API servers that give generated tools additional knowledge.
The result is a development workflow where new CLI capabilities go from request to working command in minutes instead of days, without manual coding. By the end of this post, a single natural language prompt will have produced a complete, installable CLI. That CLI can extend itself with new tools, refine them iteratively, and discover relevant MCP servers through an interactive selection workflow.
II. Solution Overview
The Challenge
As an example, consider a platform engineering team that produces weekly operations reports for leadership. Every Monday morning, stakeholders expect a summary of their AWS footprint, including which Amazon DynamoDB tables are running hot, which Amazon Simple Storage Service (Amazon S3) buckets are growing fastest, and who made significant infrastructure changes last week. The AWS CLI can list tables and buckets, but it cannot produce these reports.
Each report is a multi-step workflow that involves calling several APIs, joining the data, computing derived metrics like estimated monthly cost or growth rate, and formatting the output for a specific audience. The team ends up writing Python scripts for each report, and every new report request means another script by a developer.These are each their own small project, often requiring a hundred lines of Python to pull multiple APIs, compute derived metrics, and format output before you even think about error handling. Requirements shift weekly, so each change means modifying source code, testing, and redeploying. The tooling never converges; the team ends up with a folder of disconnected scripts, each with its own argument parsing, error handling, and output formatting. Any team that builds small, purpose-built utilities faces the same friction, and operations reporting is the example we use to illustrate the meta-tooling pattern.
The Solution
Prerequisites
To follow along with this post, you will need:
Python 3.12 or later
An AWS account with Amazon Bedrock access enabled for Anthropic Claude models in us-west-2
AWS credentials configured locally (via `aws configure` or environment variables)
Git installed (for tool version tracking)
The source code is available on GitHub. Installation instructions are in the repository README.
Walkthrough
Instead of writing report scripts manually, organizations describe what they need in natural language.
MCP servers are discovered automatically, wherein the system detects keywords like “DynamoDB”, “S3”, and “CloudTrail” in the description, searches the MCP registry for relevant API servers, and presents an interactive selection prompt for choosing which servers to include.
Once the user confirms, the system generates complete Python code for each command. These are not stubs or placeholders that users may typically see within generated code, but working implementations with validated AWS SDK for Python (Boto3) calls, error handling, and type hints.
Finally, the output is packaged as an installable Python project with a pyproject.toml file and entry points configured.
Most importantly, the generated CLI includes a tool command group that enables self-extension at runtime. After installation, users can ask the CLI to create entirely new reporting tools and iteratively refine them without touching source code. This is the repeatable part of the pattern because any generated tool inherits the ability to extend itself. This mechanism is built into every generated CLI, so each one is immediately capable of growing beyond its original scope.
III. Technical Implementation
Strands Agents SDK Integration
The Strands Agents SDK is the backbone of the meta-tooling pattern. It provides three features that make self-extending tools possible, and these features are not specific to CLI generation. Any Python application can use them to dynamically create and manage capabilities at runtime.
The @tool Decorator
When a user asks a generated CLI to create a new tool, Claude Opus 4.6 on Amazon Bedrock produces Python code that uses the Strands @tool decorator. This decorator registers the function with Strands’ tool system, making it immediately discoverable and executable:
from strands import tool

@tool
def list_s3_buckets_with_costs() -> List[Dict[str, Any]]:
The @tool decorator registers the function’s signature, type hints, and docstring as a tool specification that the Strands Agent can reason about and invoke.
Runtime Tool Loading
The Strands Agents SDK includes a tool loading system that can discover and import @tool-decorated functions from Python files at runtime. Tools do not need to be registered at application startup. They can be created, saved to a directory, and made available to the agent dynamically.In our implementation, generated tools are saved as standalone Python files in a directory called `tools/`. Each time a CLI command runs, the application scans this directory, loads any @tool-decorated functions it finds, and adds them to the agent’s tool collection without requiring a restart.The self-extending pattern works because of this scan-on-invocation approach. A user can create a tool, execute it, decide it needs changes, update it, and execute again without any rebuild or reinstall step since each CLI invocation discovers and loads whatever tools exist on disk.
Agent Orchestration with BedrockModel
The Strands Agent class ties everything together. It connects to Amazon Bedrock via BedrockModel and manages a collection of tools:
from strands import Agent
from strands.models import BedrockModel

agent = Agent(
    model=BedrockModel(
        model_id=""
    ),
    tools=[shell_tool, editor_tool] + loaded_tools,
    system_prompt="You are a tool creation assistant..."
)
When the agent receives a tool creation request, it calls Amazon Bedrock to generate the implementation and saves it as a Python file in the tools/ directory. The next CLI command automatically discovers and loads the new tool.
Amazon Bedrock Integration
CLI Creator connects to Anthropic’s Claude through Amazon Bedrock’s cross-region inference profile. Amazon Bedrock serves two distinct roles in the system.
Role 1: CLI Requirements Analysis with Structured Output
When you run cli-creator create, the first step is analyzing the natural language description and extracting a structured specification. Instead of parsing raw text from the model, we use the Strands Agents SDK’s structured output feature with Pydantic models to guarantee the response conforms to our schema:
from pydantic import BaseModel, Field
from strands import Agent
from strands.models import BedrockModel

class CommandSpec(BaseModel):
    name: str = Field(description="Command name in kebab-case")
    description: str = Field(description="What this command does")
    arguments: Optional[List[str]] = Field(default_factory=list)
    options: Optional[List[CommandOption]] = Field(default_factory=list)

class CLIRequirements(BaseModel):
    cli_name: str = Field(description="CLI name in kebab-case")
    description: str = Field(description="One-line description")
    commands: List[CommandSpec] = Field(description="Commands to generate")
    dependencies: List[str] = Field(default_factory=list)

# Create agent and invoke with structured output
agent = Agent(
    model=BedrockModel(model_id="us.anthropic.claude-opus-4-6-v1"),
    system_prompt="You are an expert CLI designer..."
)

result = agent(
    f"Analyze this CLI description: {description}",
    structured_output_model=CLIRequirements
)

# Access the validated Pydantic model — no JSON parsing needed
requirements: CLIRequirements = result.structured_output
By passing the structured_output_model, the Strands Agent constrains the model’s response to match the Pydantic schema. The result is a validated Python object where if the model’s first attempt does not conform to the schema, Strands automatically sends the validation errors back to the model and retries, producing a correct response without manual intervention. This approach eliminates malformed JSON, missing fields, wrong types, and hallucinated structure.
Role 2: Complete Command Generation with AI Functions
The second Amazon Bedrock role is generating complete command implementations. Direct integration of AI agents in code generation workflows is often avoided because of the model’s non-deterministic nature. There is no guarantee that generated code will compile, follow the expected structure, or avoid common pitfalls like empty error handlers. Strands AI Functions addresses this through runtime post-condition checking. AI Functions is a Python library for building reliable AI-powered applications through a new abstraction of functions that behave like standard Python functions but are evaluated by reasoning AI Agents. You decorate a function with @ai_function, write its prompt as a docstring with curly-brace placeholders, and attach post-conditions that the output must satisfy. If any post-condition fails, AI Functions automatically initiates a self-correcting loop, sending the specific error back to the model and retrying until all conditions pass or the maximum attempts are reached.
We use AI Functions to build a self-correcting code generation pipeline. Each generated command must pass three post-conditions before it is accepted:
from ai_functions import ai_function, PostConditionResult

def check_syntax(response: str) -> PostConditionResult:
    try:
        compile(response, '<generated>', 'exec')
        return PostConditionResult(passed=True)
    except SyntaxError as e:
        return PostConditionResult(
            passed=False,
            message=f"Python syntax error on line {e.lineno}: {e.msg}. Fix: {e.text}"
        )

def check_has_decorator(response: str) -> PostConditionResult:
    if '@cli.command' in response:
        return PostConditionResult(passed=True)
    return PostConditionResult(
        passed=False,
        message="Missing @cli.command() decorator."
    )

@ai_function(
    post_conditions=[check_syntax, check_has_decorator, check_no_empty_try],
    max_attempts=3
)
def generate_click_command(command_name: str, description: str, ...) -> str:
    """
    Generate a complete Click CLI command function in Python.

    Use @cli.command() decorator. Include needed imports using 'from X import Y' style.
    Always use 'import click' and reference as click.echo(), click.style().

    Command: {command_name}
    Description: {description}
    """
The @ai_function decorator turns the function’s docstring into a prompt template. Curly-brace placeholders like {command_name} are filled from the function arguments at call time. Each post-condition receives the model’s response and returns a PostConditionResult. When a condition fails, AI Functions sends the error message back to the model and retries automatically, up to max_attempts. The model sees the specific failure (“syntax error on line 42”, “missing @cli.command decorator”, “empty try/except block detected”) and corrects it on the next attempt.
The prompt embedded in the docstring still enforces coding conventions (use import click rather than from click import, use from X import Y for all other imports) to prevent import conflicts. Post-conditions catch what the prompt misses, making the pipeline significantly more reliable than prompt engineering alone.
MCP Server Discovery and Integration
The Model Context Protocol adds automatic discovery of external API knowledge to the pattern. When your tool description mentions AWS services, the system searches for MCP servers that can provide domain-specific tooling. Generated tools can tap into live, structured API knowledge beyond what Amazon Bedrock knows at generation time.
How Discovery Works
The system uses Amazon Bedrock to extract API keywords dynamically. The api_keywords field is part of the same CLIRequirements Pydantic model used for structured output, so keyword detection happens in the same call that extracts commands and dependencies at zero additional cost:
class CLIRequirements(BaseModel):
    cli_name: str = ...
    commands: List[CommandSpec] = ...
    dependencies: List[str] = ...
    api_keywords: List[str] = Field(
        default_factory=list,
        description="API/service keywords to search for MCP servers"
    )
When the model returns keywords like ["dynamodb", "s3", "cloudtrail"], the system uses a Strands Agent with the http_request tool from Strands Agents Tools to search the MCP registry for each keyword. Results are merged and deduplicated.
Interactive MCP Selection
After discovering relevant MCPs, the system presents them to the user for selection:
Selected MCPs are configured in the generated CLI’s .mcp.json file, and a bridge module is copied to the output project. This bridge connects to MCP servers at runtime, extracts their tool metadata, and converts them into Strands @tool functions that the Agent can invoke.
After MCP selection, CLI Creator generates each command sequentially using AI Functions. Here, the unused-buckets command initially fails the check_has_decorator post-condition for missing the @cli.command decorator, and AI Functions automatically retries generation with the error fed back to the model, producing valid code on the second attempt. All commands go through this process before having an installable CLI.
The Meta-Tooling Workflow: Create, Update, Revert
The most distinctive feature of the pattern is the iterative tool refinement workflow. This is where meta-tooling becomes practical, and it is the part most easily adapted to domains beyond CLI generation.
Step 1: Install and verify the generated CLI
After generation completes, install the CLI and verify it works:
Each command is fully implemented. Here is unused-buckets pulling live S3 data:
After installation, the CLI is ready to use. Each subcommand supports --help for detailed parameter information.
Step 2: Create a new reporting tool at runtime
Consider a scenario where leadership requests a new report that was not part of the original CLI, such as a summary of all Amazon S3 buckets with their sizes, sorted by cost impact. Instead of modifying source code, use the built-in tool create command:
Amazon Bedrock generates a complete Strands tool, saves it to `tools/`, and commits it to git. The next CLI command automatically discovers and loads the new tool from disk, so you can execute it right away:
Output is automatically formatted based on data type, so lists of dictionaries render as tables, single dictionaries display as key-value pairs, and everything else falls back to JSON.
Step 3: Update and review changes
Suppose the initial output needs adjustment. Leadership wants the report to exclude buckets with an object count of zero. The user describes this change in natural language using the tool update command.
CLI Creator commits the current version to git before overwriting, then generates a new version. The tool diff command shows exactly what changed. Now execute the updated tool to see the improvements:
The same update workflow applies regardless of what the tool does, whether it is an Amazon S3 cost report, an Amazon DynamoDB capacity analyzer, or a Salesforce data exporter.
Step 4: Revert if needed
If the update didn’t work as expected, tool revert restores the previous version from git:
The git log shows the full history of create, update, and revert operations, all tracked automatically.
Under the hood, tool create, tool update, and tool revert are convenience wrappers around git. Each operation commits to the repository, so the version history is standard git and works with any existing workflow. The tool diff and tool revert commands exist so that someone iterating conversationally can see changes and undo them without switching context to git commands, but git log, git diff, and git revert work just as well. Git-based versioning and one-command reverts make it safe to experiment.
Step 5: Output formats
Reports often need to be consumed in different ways. The --format flag lets you control how output is rendered:
The formatter attempts to use the Rich library for colored tables when available and falls back to an ASCII table implementation when it is not installed. Here is a new AWS Lambda tool stored in `tools/`, rendering as a table by default:
IV. Conclusion
The meta-tooling pattern demonstrated here combines Amazon Bedrock for code generation, the Strands Agents SDK for runtime tool management, and Model Context Protocol for external API discovery into a system where CLIs extend themselves through natural language. The implementation has clear limitations today. Generated code still requires human review before production use; post-conditions catch structural errors but cannot verify business logic correctness, and the MCP ecosystem is young enough that server coverage is uneven across domains.
V. Next Steps
CLI tools are a natural starting point because they have a well-defined structure and fast feedback loops, but the same mechanism applies to any software that could benefit from generating and refining small, composable units of functionality at runtime. Infrastructure-as-code modules, data pipeline transformations, API integration adapters, and compliance policy checks are all domains where the creation pattern is repetitive, and the validation criteria are expressible as post-conditions. To explore the pattern:
– Start with Amazon Bedrock for foundation model access.
Every computer vision model is a reflection of the data it was trained on. The precision of the labels, the consistency across annotators, the coverage of edge cases. Get the data right and the model performs. Get it wrong and no amount of architecture or compute will compensate.
AI-assisted annotation tools have made it possible to label at a speed and scale that was unthinkable a few years ago. Teams that used to spend weeks on manual labeling now generate annotations automatically and refine them. That acceleration opens up real opportunity, but it also raises the bar for the infrastructure underneath the annotation pipeline. The architecture needs to keep pace with the volume of data now moving through it.
We have spent the last decade building AI workflows and one pattern shows up consistently: the teams that treat annotation as infrastructure from day one outperform the ones that bolt it on later. The difference is not just tooling. It is the architectural decisions underneath, particularly around storage, that determine whether an annotation operation scales or stalls.
Annotation within the ML pipeline
A production ML pipeline spans data ingestion, preprocessing, training, serving, and monitoring. Annotation sits within the data layer, but it is the stage where several consequential storage decisions converge: how raw data is stored, who can access it, how long it is retained, and how it flows between labeling, training, and evaluation. Getting storage right at this layer strengthens every stage downstream.
Data gravity. A single autonomous driving project can produce terabytes of camera and LiDAR data before a single label is applied. This data needs to live somewhere durable and accessible before, during, and after annotation. It rarely moves once it lands.
Collaboration. Labeling teams may be internal, external, or a mix. Quality reviewers need the same data access as annotators. The data layer has to support concurrent access across roles and geographies without creating bottlenecks or redundant copies.
Lifecycle persistence. Labeled datasets are reused across training runs, refined as models improve, and versioned as labeling standards evolve. Storage needs to retain raw data alongside annotations for months or years.
Regulatory constraints. In healthcare, automotive, and defense, access controls around training data are subject to compliance requirements. Encryption, scoped credentials, and auditability are non-negotiable.
The teams that design for these requirements upfront build data operations that scale cleanly across the entire pipeline.
CVAT as the annotation layer
CVAT (Computer Vision Annotation Tool) started as an internal tool at Intel in 2017, was open sourced in 2018, and spun out as CVAT.ai Corporation in 2022. Millions of users use it today, and for good reason.
Annotation breadth. CVAT covers the full range of label types: bounding boxes, polygons, polylines, keypoints, skeletons, cuboids, brush-based masks, and tags. It handles images, video, and 3D point clouds natively, so teams working across object detection, segmentation, and pose estimation stay on one platform instead of stitching separate tools together.
AI-assisted labeling. Beyond SAM 3 and YOLO, CVAT supports custom models through its AI Agents framework, which lets teams plug their own inference endpoints directly into the labeling workflow. For video, SAM 2-powered tracking propagates annotations across frames. The shift from manual annotation to review-and-correct workflows is where the real throughput gains happen.
Deployment flexibility. CVAT ships in three editions: Community (free, self-hosted), Online (managed SaaS), and Enterprise (on-premises with SSO, RBAC, and audit logging). You can start hosted and move to self-hosted as data governance needs evolve.
Pipeline integration. CVAT exposes a REST API with a Python SDK and CLI, so annotation tasks can be created, populated, and exported programmatically. For teams building CI/CD-style retraining loops, this is what makes CVAT a pipeline component rather than a standalone manual step.
Backblaze B2: The storage layer that compounds
Annotation tools get the attention, but the storage layer is where the architecture compounds over time. CVAT supports native cloud storage integration through S3-compatible buckets, and Backblaze B2 fits directly into that connector. Configure your B2 endpoint, bucket name, and application key credentials, and CVAT treats it as native cloud storage.
This architecture decouples compute from storage. CVAT handles annotation logic while B2 owns durability and access, and you can scale, migrate, or replace either independently. Because B2 is S3-compatible, other stages of the ML pipeline, from training scripts to data validation to orchestration, access the same data directly from the same bucket CVAT writes to. No intermediate exports. No dataset copies drifting out of sync.
Retention is where the storage decision pays off most. Annotation datasets have long lifecycles, and footprints accumulate fast across concurrent projects. B2’s storage economics let teams hold large datasets across the full model development lifecycle without cost becoming the limiting factor. This is especially relevant for video-heavy projects and multi-sensor datasets where raw data runs into tens of terabytes.
Access control matters too. B2 application keys can be scoped to individual buckets or file prefixes with granular permissions and optional expiration, so access boundaries stay clean across annotators, labeling services, and downstream training pipelines. The CVAT integration guide for Backblaze B2 walks through the full setup, and the CVAT cloud storage documentation covers access permissions, manifest files, and endpoint routing.
Building the pipeline that scales into what’s next
The teams building the best computer vision models are not just choosing better algorithms. They are investing in the annotation infrastructure that feeds those algorithms: the right labeling platform, the right storage architecture, and the right cost structure to sustain it all as data grows.
This becomes even more critical as the field moves toward world models. NVIDIA’s Cosmos platform has already been downloaded over two million times. World Labs launched Marble for commercial 3D world generation. DeepMind’s Genie 3 produces interactive 3D environments in real time. Yann LeCun left Meta to start AMI Labs with the explicit goal of building AI systems that understand physics, not just predict text. These systems need training data that goes far beyond today’s labeled images: synchronized multi-sensor captures, physics-aware video, dense 3D point cloud annotations. The data volumes and annotation complexity will dwarf what most teams work with today, and the infrastructure underneath will need to handle it.
The annotation pipeline you build now is the one that will carry you into that future. Both layers are worth getting right early.
Welcome to our second quarterly Network Stats report covering Q1 of 2026. Along with Drive Stats and Performance Stats, Network Stats pulls back the curtain on real-world infrastructure data, particularly how network-level analytics reflect emerging AI industry trends and usage patterns.
Get more Network Stats (and the details of the dataset)
If you are curious about what metrics we’re recording and how we classify data in this series, check out the details outlined in our Q3 2025 Network Stats and Q4 2025 Network Stats report.
One of the roles of the Network Engineering (NetEng) team at Backblaze is to monitor how traffic moves into, out of, and across our platform—not just day-to-day, but over time as customer behavior and industry dynamics evolve. Right now, few forces are reshaping networks faster than AI.
With the launch of B2 Overdrive in April 2025, we built a direct, high-performance path between our storage layers and neoclouds where processing, inference, and modeling take place. It has given us a front-row seat to the impact of AI and how network behavior is changing with it. This quarter, in addition to our regular data analysis, we’ve added some geographic heatmaps to understand where and how data is moving.
Join us live for the webinar
Join us live for the Q1 2026 Network Stats webinarMonday, May 4, 2026 at 11:30 a.m. PT / 2:30 p.m. PT. We’ll explore where AI traffic concentrates, how high-magnitude data flows behave, and what early indicators suggest about the future of AI-native infrastructure design.
Can’t make it live, or reading this article after-the-fact? Sign up anyway and catch the recording on demand.
AI: The elephant in the room
AI workflows don’t just need a place to store data, they need to be able to move it quickly, easily, and nearly constantly for short bursts. Large, multi-petabyte datasets are ingested, transformed, exported for training, pulled back for evaluation, and periodically refreshed as models evolve.
Backblaze plays a key role at both ends of that lifecycle. We serve as a durable storage layer for the initial data ingestion, and as the high-throughput source feeding model training, evaluation, and validation to whatever best neocloud is suitable at the moment. Once that model has been trained, it needs to be stored, served, and periodically retrained, where we serve as the storage medium.
From a network perspective, this represents a meaningful shift from diffuse, internet-style traffic patterns to large, high-bandwidth flows between a smaller set of endpoints typical of AI-centric infrastructure.
Trends and spring renewal
The defining theme of the quarter is “winter freeze” as we observed what looks to be a quiet period of Neocloud and hyperscaler traffic over the winter months with an uptick in March.
The stacked area graph below shows total traffic by network type over time updated with the most current data. Hosting and internet service provider (ISP) traffic stayed largely within historical norms reflecting steady-state usage patterns. Three slices stand out this quarter:
CDN traffic: Increase in CDN traffic over the winter months.
Neocloud traffic: After the October 2025 peak, we saw a decline in neocloud traffic heading into January. The winter months were a low volume period with an upward trend observed February into March 2026.
Hyperscaler traffic: Hyperscaler traffic also followed the Neocloud pattern of a low period during winter with an upward trend in March 2026.
Monthly view of all bits transferred to each network type (2025-05 to current)
With more than three quarters of data at our disposal, we can now start to see some trends over time. What do we think is happening?
This could be an indication of the human element where the business cycle has a lot of downtime in the winter months—all of our code, infrastructure, computing jobs, and new innovations involve people somewhere along the chain and we all (hopefully) tend to take more time off in the winter months.
Another hypothesis is that our numbers only show bits transferred over our network links over time. If a large dataset has been stored with us, there may not need to be an update to the large stored dataset for a number of months as code and models are refined, and then suddenly a large amount of new data makes its way over our network links. Perhaps a combination of both—human and training lifecycle?
We’ll be tracking these metrics and updating in future reports, so this high-level view of network traffic segmented by network type will be interesting to watch.
Chart overview
Now let’s take a deep dive into our data and answer these questions:
Quarter over quarter heatmaps: How and where data moves
To better understand our network activity, we isolated variables like region and types of provider. Let’s look at the following dimensions:
Total traffic volume: Where did we send and receive the most traffic?
Magnitude: Where were the data transfers with the most bits per unique IP address?
Uniqueness: What does the number of distinct IP addresses look like?
Quick terminology refresher
Regions
US-West: Our largest and longest-running region
US-East: Region with the most observed proximity to neocloud infrastructure
CA-East: Our newest region in Canada.
Network Types
CDN: Networks that use Backblaze as an origin store for content delivery
Hosting: Traditional hosting providers that runs workloads like physical or virtual servers for web, database, or application tasks
Hyperscaler: Large, traditional cloud providers
ISP Regional: Local or regional ISPs, think of these as the “last mile” paths as these networks are very close to customer equipment and efficient
ISP Tier1: National or international ISPs that carry our traffic long distances
Neocloud: AI -focused compute networks
Heatmap #1: Where did we send and receive the most traffic?
US-West ISP-Regional traffic continues to be a hotspot on the heatmap, as expected. This region has the largest footprint behind it and connections to internet exchanges (IX). This quarter, with a lull in neocloud and hyperscaler traffic over the winter period, we saw an increase in traffic to our CDN partners. The amount of traffic to CDN networks in the US-West, US-East, and EU-Central regions all increased quarter over quarter.
Total number of bits transferred across our regions to each network type for Q1 2026.
Total number of bits transferred across our regions to each network type in Q4 2025.
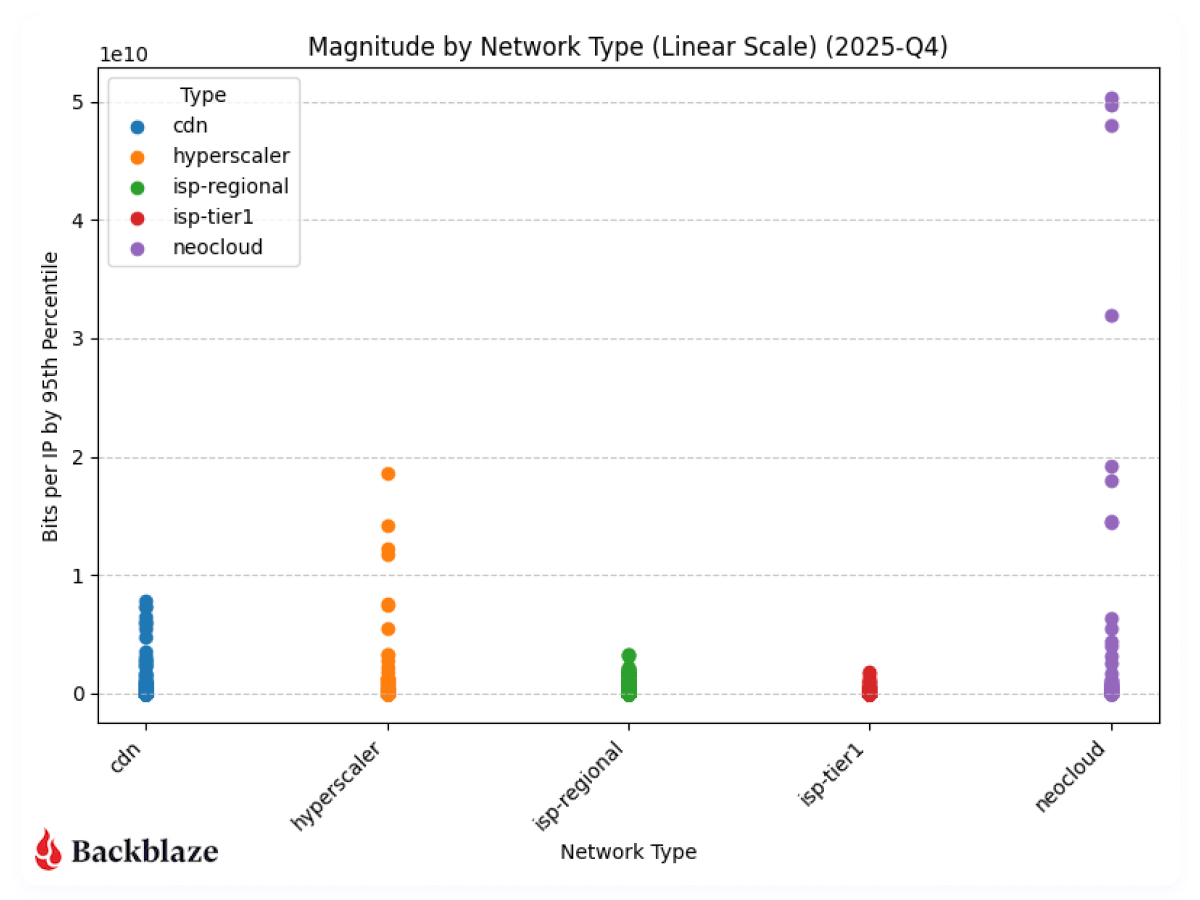
Heatmap #2: Where were the data transfers with the most magnitude (bits per IP address)?
Another metric we record is bits per IP or what we term “magnitude.” This combination of the amount of traffic transferred with how many actors are involved per network is a good proxy to measure how heavy or impactful individual data flows are. In short:
High volume, many IPs: Easier to distribute and load-balance across infrastructure. And many source and destination pairs means that we can traffic engineer at the WAN layer, sending some traffic over one provider and some over another.
High volume, few IPs: More difficult, but more interesting, from a NetEng perspective.
Despite the total amount of traffic decreasing over the winter months for neocloud traffic, the magnitude of neocloud transfers still remains high. This speaks to the nature of the traffic pattern—when a GPU/compute cluster is ingesting or producing data, it does so at a high bitrate with just a few number of unique endpoints talking to each other.
As expected, the concentration of our magnitude metric is high for our US-East cluster, with an uptick in concentration in US-West and EU-Central. Where specifically is this new concentration in these regions? Spoiler: We explore neocloud traffic later in the report with geographical data!
Magnitude transferred across our regions to each network type for Q1 2026.
Magnitude transferred across our regions to each network type for Q4 2025.
As with last quarter, we see a high concentration of neoclouds in US-East, but our new heatmap also shows a rising activity in US-West and EU-Central. We also see more distribution in other use cases.
Heatmap #3: How many unique addresses do we interact with?
Uniqueness—measured by the number of distinct IP addresses per network type—adds another dimension to the story. Unsurprisingly, the quarter over quarter heatmap looks almost identical. This is expected with our US-West region being the most mature and serving a large amount of ISP Regional consumers and is a good sanity check on our dataset.
US-West shows the highest overall uniqueness, driven by its larger number of data centers and mix of workloads.
Neocloud traffic, by contrast, tends to involve fewer, more persistent endpoints, consistent with AI pipelines that rely on stable, long-standing connections between storage and compute.
This is where we can clearly see those AI networking elephant flows showing up in the data.
Communication uniqueness across our regions to each network type for Q1 2026.
Communication uniqueness across our regions to each network type for Q4 2025.
Summary: Seasonal change in traffic flows
With a lull in bits transferred as noted in our top level graph, we can see what other networks by percentage took over. CDN traffic increased from around 20% to 32% of our total traffic, localized ISP regional traffic also increased 21.5% to 27.8%. Neocloud and hyperscaler traffic reduced from 36.4% in Q4 2025 to 25.5% in Q1 2026.
Quarter over quarter data
We’re tracking our usual metrics here, and we gave you both this quarter and last quarter’s charts so you can easily spot potential trends.
First let’s take a look at where all our traffic goes from a global perspective with an updated view of last quarter.
A Sankey diagram of all ingress and egress traffic grouped by type of network for Q1 2026.
A Sankey diagram of all ingress and egress traffic grouped by type of network for Q4 2025.
Next, let’s take a look at the geography of our network traffic. As we’ve already seen in previous heatmaps, data gravity is concentrating traffic into specific locations.
Where in the world is the neocloud?
New for March 2026, we’ve added geographic information to our dataset, allowing us to take a look at the concentration of traffic based on network types. We’re taking a look into the following locational slices:
Countries
Countries excluding the United States
U.S. states
Heatmap #1: What countries show the highest concentration of traffic by network type?
Neocloud, hyperscaler, and CDN traffic in our dataset all show high concentrations in the United States. Is this due to our US-West and US-East regions being the largest of our deployments or is it related to how certain traffic types are present in the emerging AI market? A quick search shows that the U.S. contains around 40-45% of all data centers globally, so it’s likely the sheer deployment size and scope of US sites aligns with what we’re seeing at the network level.
Total number of bits transferred by network type to countries from March 2026.
That said, excluding outliers can show us additional geographic trends, which leads to our next heatmap.
Heatmap #2: If we exclude the U.S., what countries show the highest concentration of traffic by network type?
Since the United States numbers highly skew the heatmap concentration, below is a heatmap without the US to give us better fidelity on ex-US datapoints. Interesting to note that we deliver a large amount of traffic to CDN entities in the Netherlands. This is due in part to our connectivity to AMS-IX (Amsterdam Internet Exchange).
The network posture of Europe differs from the United States to where local IX networks are preferred over larger Tier1 ISP networks for transit (politically, cost, and preference wise). Second up is Singapore for CDN content and hosting activity in Germany. The next standout is a concentration of neocloud related activity in Finland, Brazil, France, and Canada.
Total number of bits transferred by network type to countries, excluding the United States, from March 2026.
Heatmap #3: What U.S. States show the highest concentration of traffic by network type?
If we dive into just the U.S. States, we can see the heavily weighted concentration of neocloud traffic to and from California. Hyperscaler activity matching up with our expectations as California and Virginia (specifically the Ashburn and Reston corridor) have a high concentration of partner networks. CDN traffic for us concentrates more for Backblaze specifically since the US-West region is our largest cluster footprint and longest running sites, so naturally the data being served out of these sites is more long-lived content lifecycle wise.
Total number of bits transferred by network type to US States from March 2026.
These insights into data geography help us understand, plan, and modify our growth trajectory. I say “help,” because we’re also discovering that neocloud and hyperscaler activity is very bursty and has a high magnitude of traffic flow below. From a planning perspective, understanding whether those bursts translate to a higher baseline for increased demand—and how to support bursts when they happen—is a different conversation than the predictable network trends of years past.
Neocloud and hyperscaler traffic vs predictive patterns
This quarter we’re sharing a deeper dive into the metrics associated with neocloud and hyperscalers over time. These two traffic types are driving innovation at Backblaze and are interesting to share to the larger industry. While CDN, hosting, and ISP regional traffic patterns are easy for us to model and account for as we manage our network infrastructure, neocloud and hyperscalers growth profiling are a challenge! As we said above, they are bursty and have a high magnitude (bits per associated IP address).
And, in the spirit of that conversation, we have several new views to share:
Neocloud and hyperscaler magnitude (bits per IP address) over time
Heatmaps over time
Neocloud
Hyperscaler
CDN
Hosting
ISP regional
Chart #1: What’s the magnitude of neocloud and hyperscaler traffic over time?
Matching our earlier charts, we saw a burst of activity from August to December of last year with a resurgence of high magnitude neocloud traffic in March of 2026.
Magnitude of neocloud and hyperscaler related traffic over time.
Heatmap #1 and #2: How dynamic are neocloud and hyperscaler traffic patterns?
Neocloud and hyperscaler traffic patterns are the most impactful to our operations due to the magnitude of their data flows. Below is a more detailed look at these concentrations over time, with a burst of activity from August to November for Neoclouds, a quiet period over the winter months, and a pickup again in March.
As expected our US-East region remains a hotspot of Neocloud related activity. One standout from this analysis is that the Neocloud activity in March is more spread out over our US-West, US-East, and EU-Central regions. It will be interesting to see if this spread grows or contracts over time.
Neocloud monthly traffic totals by region for May 2025–March 2026.
Over the winter months, there was a noticeable decrease in activity for hyperscale related traffic, most notable in January, but when compared to neocloud traffic, the month-over-month traffic patterns remained strongly visible in our US-East region.
Hyperscaler monthly traffic totals by region for May 2025–March 2026.
Heatmap #3, #4, and #5: How dynamic are CDN, hosting, and ISP regional traffic patterns?
We’re grouping CDN, hosting, and ISP regional types together because they represent a “steady-state” for us as network operators. These patterns are predictable, spread out over time, and generally do not change month-to-month. We do see visible bursts of traffic, like with a heavy blue tile for CDN in September and a few areas of hosting related traffic in May and October of 2025, but overall these are less impactful to our operations because the magnitude (bits per unique IP address) is lower—many sources are talking to many destinations, which as operators is easy to load balance.
CDN monthly traffic totals by region from May 2025–March 2026.
Hosting monthly traffic totals by region for March 2025–May 2026.
ISP Regional monthly traffic totals by region for March 2025–May 2026.
The most striking example of this predictability is, unsurprisingly, ISP regional traffic. This represents your more consumer driven workflows and use cases.
Neocloud business cycle and geography
We can draw a conclusion from all these charts: neocloud and hyperscaler are both different traffic patterns and far more dynamic than CDN, hosting, and ISP regional traffic. For our Network Engineering group, this means we have two different stylistic approaches towards managing our network.
First, when planning for the neocloud and hyperscaler traffic, our solutions entail adding large amounts of additional bandwidth in increments of 100G and often 400G ports to handle burst rates, ensuring that our inter-switch links inside our datacenter can also handle bursts of traffic, and reaching out to select partners to establish private network-to-network interface (PNI) connections where appropriate for zero-settlement transit.
Our steady state growth patterns stem from CDN, hosting, and ISP regional traffic with easy to model growth curves. Looking over monthly numbers indicates a clear pattern for us, and that’s easy to plan for.
The last factor that we’re placing more emphasis on is the geographical location of our network interconnections. We’re seeing a high concentration of demand located in the United States, specifically in regions like California, Virginia, Illinois, and Georgia.
With more datapoints, we can clearly see the magnitude of the neocloud and hyperscaler transfers when compared to other network types. As above, it’s a bit early to claim concrete quarter over quarter patterns, but we’ll keep monitoring and updating the dataset.
What’s next?
Anything specific you want to see? Let us know in the comments or reach out to the Network Stats team. Or, keep up-to-date with the latest technical content with our Developer Newsletter.
NAB Show 2026 wrapped up last week in Las Vegas, and we left with something special in hand: the NAB Show Product of the Year Award in the Cloud Computing and Storage category—this time for Backblaze B2 Neo.
It’s a meaningful recognition, and one that reflects where we see the media and AI infrastructure market heading. Here’s a look at what the recognition means, and why B2 Neo matters.
What this recognition means
Winning the NAB Product of the Year Award reflects something we genuinely believe: that storage infrastructure is a foundational capability for modern media and AI platforms, not an afterthought or a separate vendor relationship to manage.
The NAB Show brings together the best of the media and entertainment industry, and having B2 Neo recognized in this context—among platforms solving real, production-scale problems across streaming, OTT, AI-driven media processing, and large-scale content delivery—is meaningful validation that the approach resonates.
B2 Neo launched in February 2026 and is already supporting production workloads including AI training pipelines, high-performance computing environments, and large-scale media delivery. The response from platform providers has reinforced what we know: organizations want to offer integrated, high-performance storage without building it from scratch, and they want the economics to make sense.
What is B2 Neo?
B2 Neo is a high-performance, S3-compatible cloud object storage solution purpose-built for platforms running data-intensive media and AI workloads. But describing it simply as “cloud storage” undersells the point.
The key distinction: B2 Neo is a white-label service. Rather than selling storage directly to end users, B2 Neo enables platform providers—like media workflow vendors—to offer fully integrated storage under their own brand. Partners launch their own storage service with custom endpoints, pricing, and user experiences, without having to build or operate the underlying infrastructure themselves.
The result is that platforms can go from “we don’t offer storage” to “we have a native, high-performance storage tier” in weeks rather than years, with none of the capital investment or engineering overhead that building it in-house would require.
Why it was built
The problem B2 Neo addresses has been growing for years, but it’s become acute as streaming, OTT, and AI-driven media workflows scale up.
Compute has gotten fast, distributed, and relatively affordable. GPU clusters, edge networks, and CDNs can all handle increasingly complex workloads. But storage has often lagged behind—fragmented across providers, expensive to move data in and out of, and either too costly or too operationally burdensome to build in-house.
The consequence is real: GPU clusters sit idle waiting on data. Streaming pipelines bottleneck on access speeds. Media organizations duplicate content across storage systems because no single layer integrates cleanly into the rest of the stack.
B2 Neo was designed to remove that bottleneck. It delivers up to 1Tbps of throughput to ensure that compute resources—GPU clusters, streaming systems, edge delivery networks—are never waiting on storage. It combines that performance with Backblaze’s 17+ years of operational experience at exabyte scale, and wraps it in an API-first architecture that plugs directly into partner platforms.
How it works
From a technical standpoint, B2 Neo delivers high aggregate throughput using cost-efficient, disk-based infrastructure with strategically deployed flash layers—a write-through cache design that captures the performance benefits of flash without the cost and scalability limitations that come with an all-flash architecture at the multi-petabyte scale that media and AI workloads require.
For workloads where throughput matters as much as latency—moving large video files, training AI models, serving content at scale—this approach is particularly effective. It allows platforms to maintain a centralized data repository and efficiently deliver data to compute providers, edge networks, and CDNs without duplicating data across storage systems.
API-driven provisioning lets partners programmatically create and manage storage accounts, permissions, and billing within their existing systems. Whether a partner is running an OTT platform, a media asset management system, or an AI training pipeline, B2 Neo integrates as a native extension of that environment rather than an external dependency to work around.
Included egress and free API calls round out the picture, eliminating the usage-based fees that typically make storage decisions financially complicated.
What’s next
This is a product that will keep evolving alongside the media and AI infrastructure landscape. We’re working closely with early partners to expand B2 Neo’s capabilities—performance, integration depth, provisioning flexibility—and we’ll have more to share as those conversations develop.
If you’re building or operating a platform that would benefit from embedded, high-performance storage, we’d love to talk. Reach out to our team to learn more about what a B2 Neo partnership looks like.
Bandwidth purchased for data center connectivity surged by nearly 330% between 2020 and 2024, driven primarily by AI workloads. And in 2024, just 10 buyers accounted for nearly 62% of all purchases, according to Zayo’s Bandwidth Report. That concentration is a structural feature of how AI moves data.
Every training run that pulls data from Backblaze storage to a neocloud passes through our network, and our telemetry captures what those flows look like in real time. Our Q4 2025 Network Stats report covers a full quarter of that data. It shows AI workloads producing a distinct network signature: sustained, high-volume transfers between a small number of endpoints, with infrastructure requirements specific enough to be worth examining in detail.
This piece walks through what that signature looks like and what it means for the infrastructure decisions teams are making right now.
The AI model lifecycle and how it moves data
AI model development is a cycle. Large datasets are ingested and consolidated, exported to compute for training, pulled back for evaluation, then pushed out again as models are refined, retrained, and updated with new data. Each stage requires moving substantial volumes of data between storage and compute, repeatedly, over the life of a model.
That structure produces a specific kind of network traffic. AI training moves petabyte-scale data between storage and compute nodes in sustained, long-lived flows—what network engineers call elephant flows—with training jobs running for hours or days under continuous network load. Add frequent checkpointing, model updates, and periodic data refreshes, and the result is traffic that is high in volume and persistent across the entire training run.
This shows up clearly in the Q4 2025 Network Stats data. Neocloud traffic spiked sharply from July through November, peaking in October, then settled into a higher baseline heading into the new year. One interpretation of that shape is the AI lifecycle playing out across a concentration of large training cycles: ingestion, training egress, then a new steady state as stored models get served and periodically retrained. As we accumulate more quarters of data across a broader customer mix, we’ll be better positioned to distinguish that pattern from seasonal budget cycles or customer-specific factors.
Backblaze network traffic for Q4 2025.
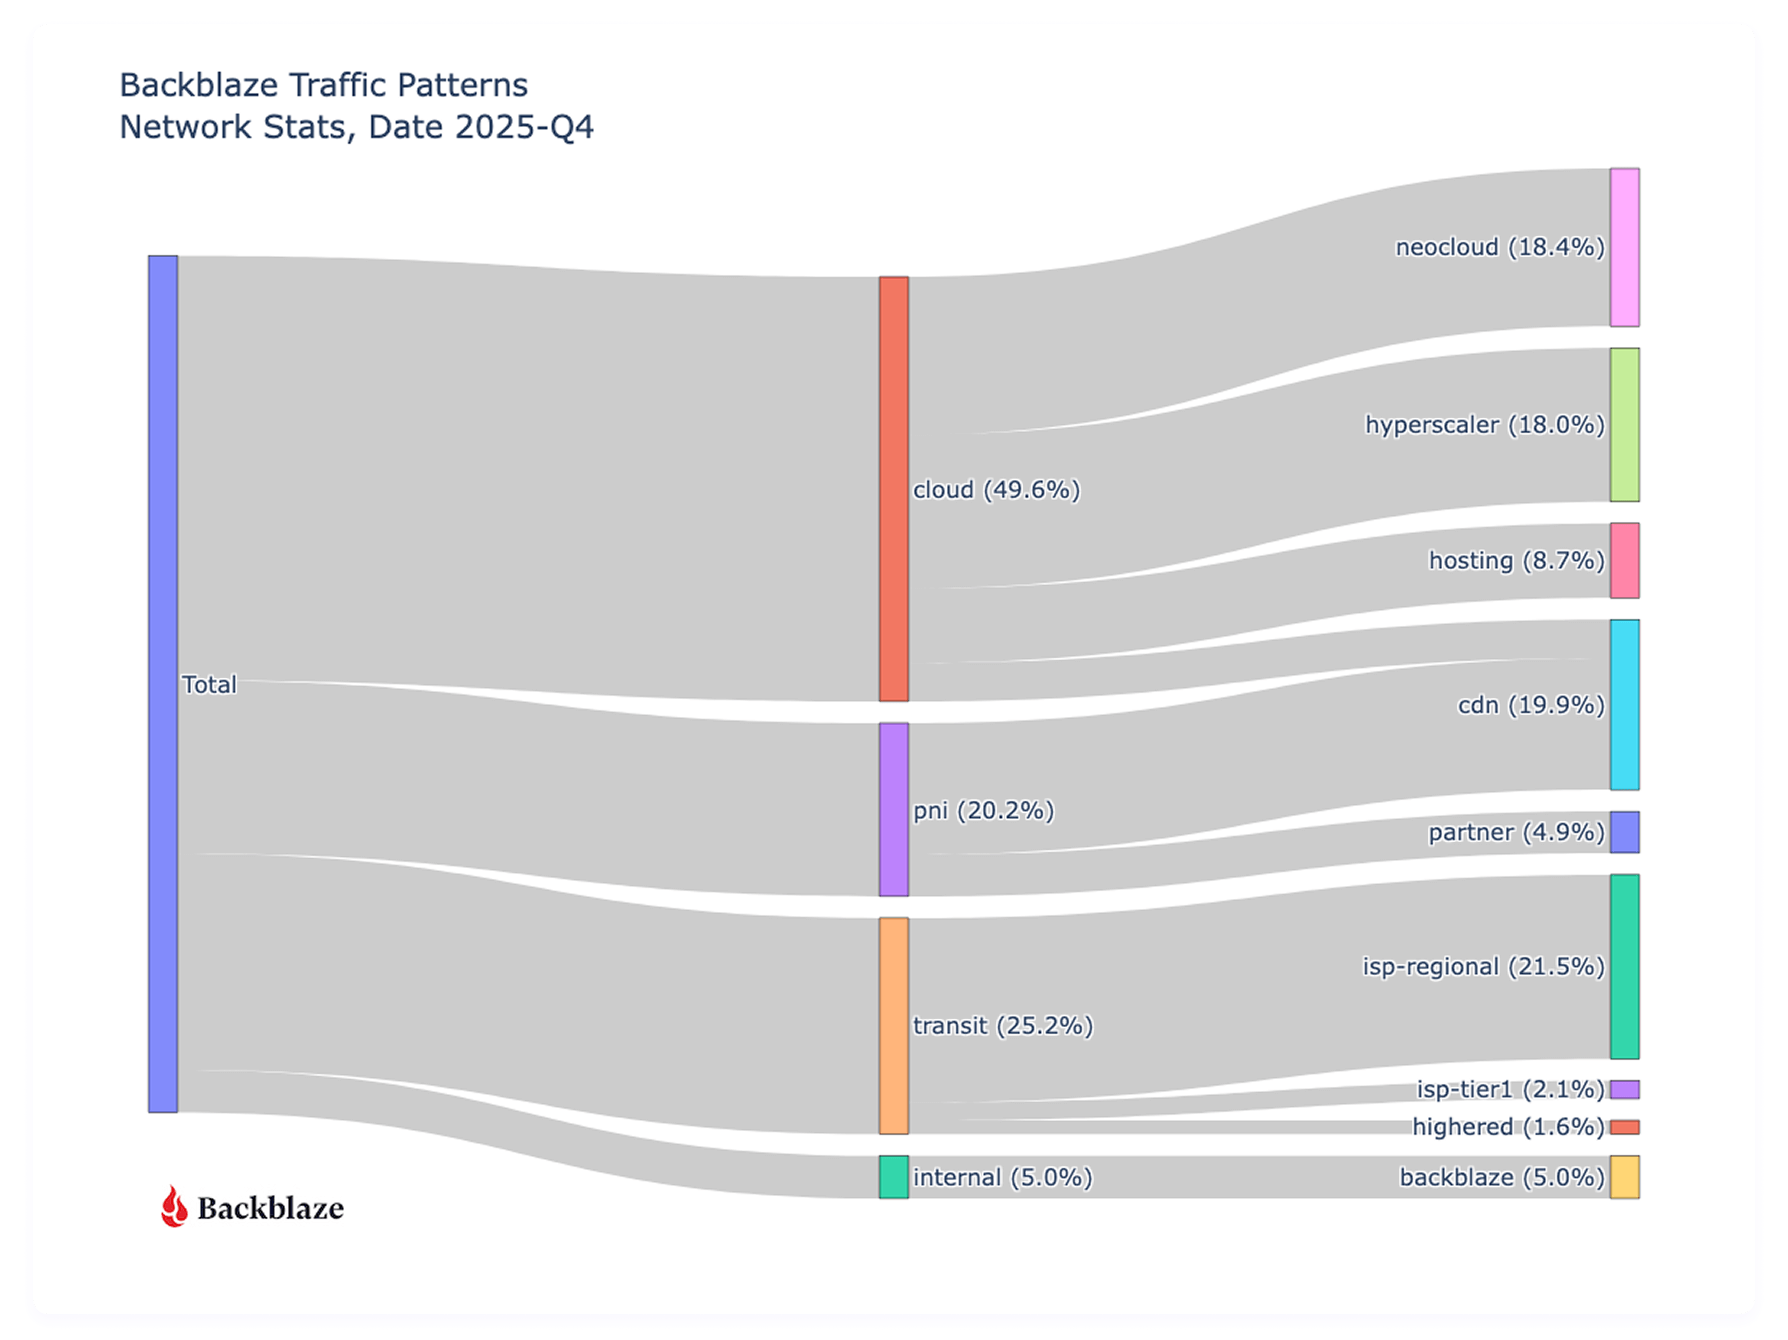
Also visible in the Q4 data is where this traffic is going. Cloud-to-cloud traffic grew from 36.2% to 49.6% quarter-over-quarter, with hyperscaler destinations rising from 3.5% to 18%. As the report notes, it’s too early to call these statistically significant trends; the dataset reflects Backblaze’s specific customer mix and covers a single quarter. The direction is consistent with how AI teams operate in practice: moving workloads across neoclouds and hyperscalers depending on price, availability, and job requirements. The storage layer is what persists across those compute environments, which has direct implications for how it needs to be designed.
What elephant flows require from a network
Traditional cloud infrastructure is designed around a specific traffic profile: many clients, many sessions, many discrete transactions. Routing, load balancing, and edge capacity are all optimized for that pattern, distributing load broadly and handling high volumes of short-lived connections efficiently.
Elephant flows don’t fit that profile. AI training establishes persistent, high-volume connections between client and storage that sustain continuous data movement for hours or days at a time. These connections are stickier than typical cloud traffic, particularly on peered networks, and the strain they produce is concentrated rather than distributed—showing up primarily at the edge, where routers handle sustained throughput at scale. Most traditional cloud infrastructure wasn’t provisioned for that kind of sustained pressure at the edge, because most workloads don’t produce it. Internal to the network, depending on a myriad of things—object size, concurrent threads, hardware, internal routing logic—your network path being sticky doesn’t reduce the number of I/O operations for servers, and often that becomes one of the biggest bottlenecks.
The stakes make this consequential. Training the most advanced models now costs hundreds of millions of dollars, according to Epoch AI—though we also know this is a new technology, and therefore likely the compute will get more efficient over time. That said, the storage is still storage: Data has to live somewhere.
Infrastructure that can’t sustain throughput under continuous load doesn’t just slow training down; it adds cost to every run. The practical answer is building throughput capacity at the connection points between storage infrastructure and the internet or peer network, sized for sustained flows rather than peak bursts.
That’s what AI-grade storage infrastructure is designed around: sustained throughput to a small number of destinations, at 100Gbps to 1Tbps per transfer for the largest AI workflows. Achieving that in practice means rethinking how a network is designed, routed, and scaled. We’ve written separately about what that looked like for Backblaze’s own infrastructure. Latency matters here for a specific reason: on long-distance transfers, higher latency directly limits achievable sustained throughput, which is one reason why geographic proximity to compute infrastructure affects real-world performance.
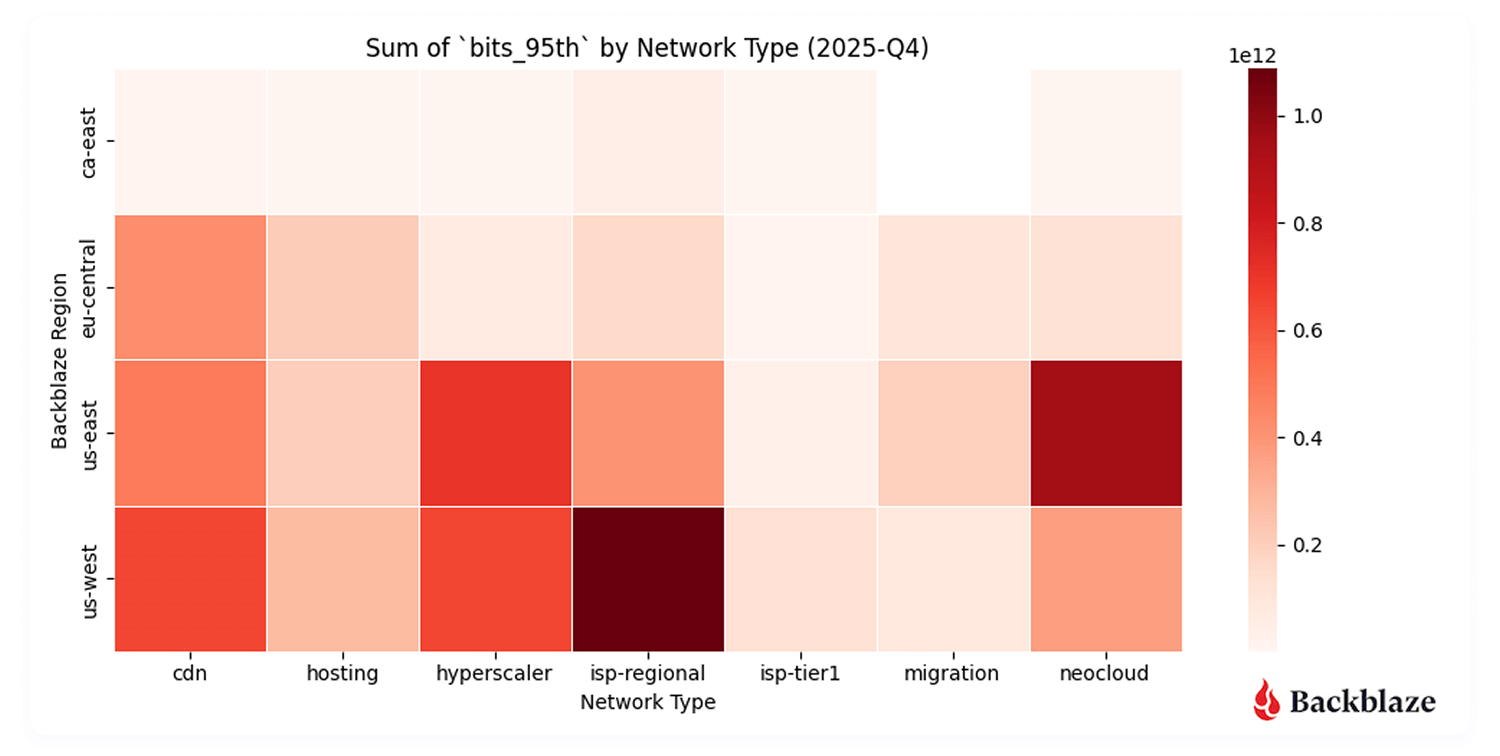
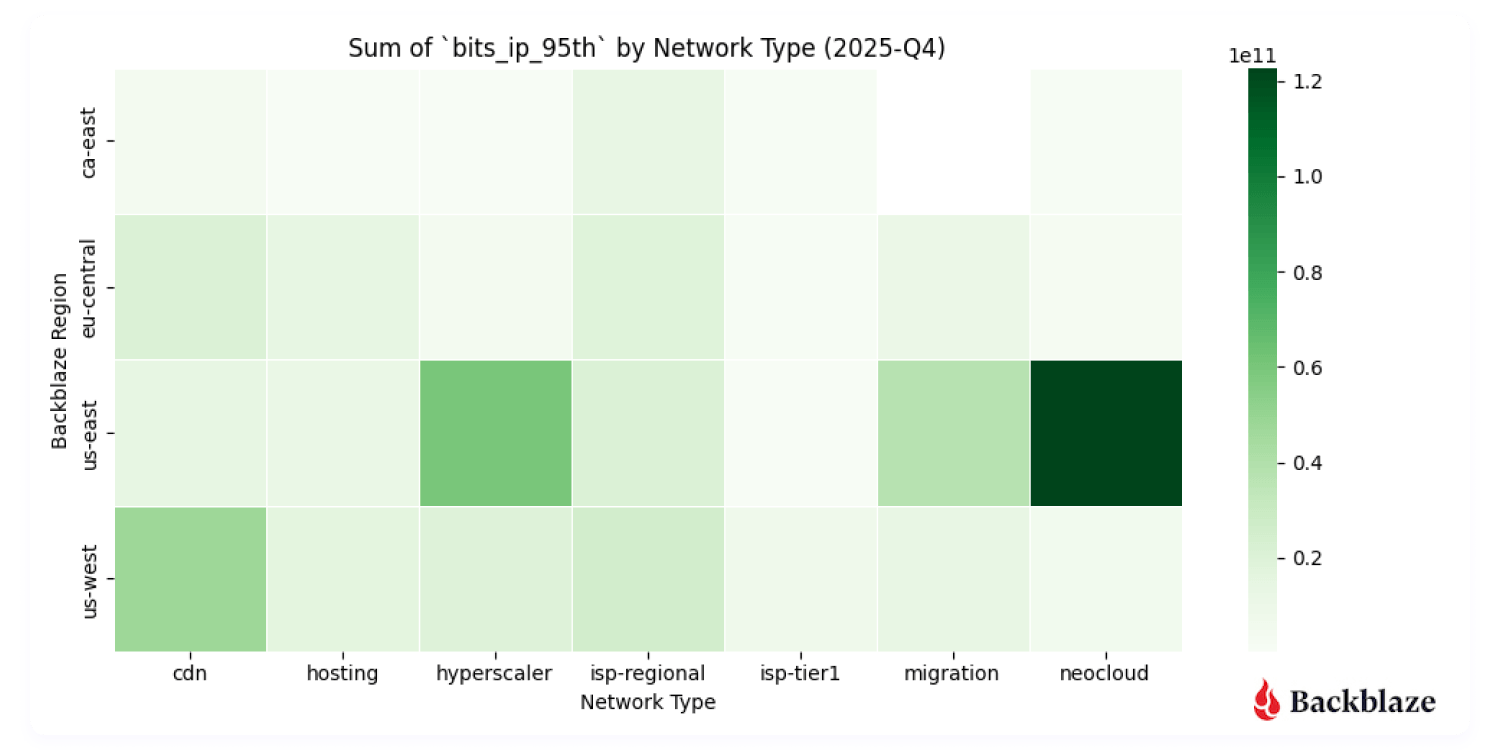
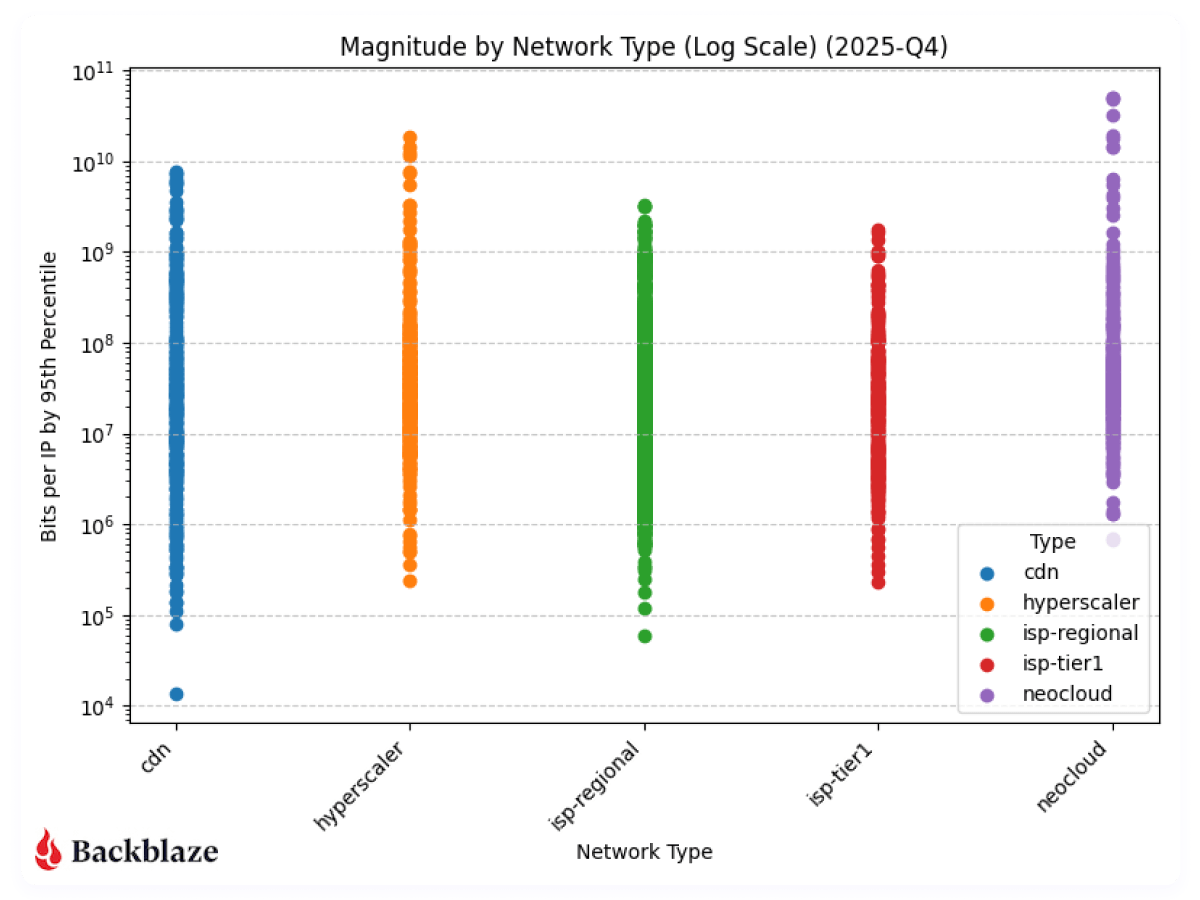
The Q4 Network Stats heatmaps show this pattern from two angles. The magnitude heatmap, measuring bits transferred per unique IP address, shows high-magnitude neocloud flows clustering clearly in regions serving AI-heavy compute endpoints. The uniqueness heatmap shows neocloud traffic involving fewer, more persistent endpoints than CDN or ISP traffic, consistent with AI pipelines that rely on stable, long-standing connections between storage and compute.
The geography of AI infrastructure
The heatmaps show where AI traffic concentrates geographically today. Neocloud activity in the Q4 dataset clusters in Chicago, Dallas-Houston, Denver, New York, the Northern Virginia Reston/Ashburn corridor, and Atlanta, with a clear skew toward the East Coast. This reflects where AI compute infrastructure was built first and remains densest. Keeping latency low between storage and compute is a prerequisite for sustaining the high throughput rates AI workflows require, and that constraint has historically made East Coast proximity an advantage.
Magnitude transferred across our regions to each network type in Q4 2025.
That concentration is consistent with broader infrastructure dynamics. AI training workloads are driving demand for regions with available power, fiber density, and compute infrastructure, and power constraints in preferred markets are already forcing operators to explore secondary locations and invest in custom power infrastructure. Demand in markets outside traditional data center hubs is growing rapidly as a result: Metro bandwidth in Memphis grew from 0.3 terabits to 13.2 terabits between 2023 and 2024. On the flip side, building out cabling to those traditionally under-utilized locations is expensive, often adding thousands of dollars per month to data center economics. High-capacity interconnects are central to making those secondary locations viable; without them, the compute investment is stranded.
The scale of what’s being built reflects the trajectory of the workload. AI training infrastructure is projected to grow at a 22% compound annual growth rate (CAGR) through 2030, reaching more than 60GW of capacity, while inference infrastructure is expected to grow faster still at 35% CAGR, reaching more than 90GW, according to McKinsey. Training and inference have different geographic requirements: training tolerates latency and can sit in power-rich remote locations, while inference needs to be close to users, which means the buildout will be distributed across both dense metro markets and secondary locations connected by high-capacity fiber.
Backblaze’s own infrastructure decisions reflect this pattern directly. The East Coast concentration drove the decision to double Backblaze’s US-East footprint. At 100Gbps and above, proximity to where AI compute is actually running is a determining factor in storage performance.
What AI-ready storage infrastructure actually means
Storage has traditionally been sized for capacity and evaluated on cost per terabyte. AI workflows change the calculus. When a training run is pulling petabytes of data from object storage to flash storage at sustained 100Gbps rates, the storage layer is as much a performance determinant as the compute layer. A storage system that can’t sustain those throughput rates creates a bottleneck that no amount of GPU capacity can compensate for.
Throughput capability is one requirement. Portability is the other. The multi-cloud behavior visible in the Q4 data reflects how AI teams actually operate: moving workloads to whichever compute provider offers the best price-performance for a given job. Storage that is tightly coupled to one cloud provider is structurally incompatible with that workflow. Data that can’t move freely across cloud environments becomes a constraint on the model development process.
This is the infrastructure problem Backblaze B2 Overdrive is designed to address. By building a direct, high-performance path between Backblaze’s storage layer and the neoclouds where AI processing takes place, it provides the sustained throughput that training workflows require alongside the portability to move data as compute requirements change. The connections between Backblaze and neocloud endpoints visible in the Q4 heatmaps represent that architecture in practice.
The point extends beyond any single product. As AI workloads become a larger share of overall data center activity, the criteria for evaluating storage infrastructure are shifting. Capacity and cost per terabyte remain relevant, but sustained throughput capability, interoperability with compute providers, and network proximity to AI infrastructure are becoming equally important factors. Teams that treat storage as a passive component in AI pipeline design are likely to find it becomes the active constraint.
Early signal, long trend
The Q4 2025 Network Stats data is one quarter of observations from one storage provider’s network. The patterns it shows—high-magnitude flows to a small number of endpoints, East Coast geographic concentration, rising cloud-to-cloud traffic, a higher baseline heading into the new year—are consistent with what the broader industry understands about how AI moves data. What’s new is that they’re visible in real network telemetry rather than modeled projections.
We’ll be watching how neocloud traffic concentration evolves regionally, how the training-to-inference ratio shifts as inference infrastructure scales, and whether the cloud-to-cloud growth visible this quarter continues.
The full dataset, methodology, and visualizations are in the Q4 2025 Network Stats report. For background on how we classify and measure network traffic, the Q3 2025 report covers the dataset in detail, and you can follow the whole series here.
Modern media workflows don’t run on storage alone. They run on ecosystems—tightly integrated stacks of tools that ingest, process, analyze, move, review, and distribute content at scale. The companies we partner with aren’t just integrating with Backblaze; they’re building on it to solve real, specific problems that media teams face every day: archives that are impossible to search, file transfers that collapse over distance, review cycles that slow production to a crawl, compliance workflows that can’t keep up with library growth.
At NAB Show 2026, we’re bringing ten of those partners into booth N1259 to share what they’ve built. But the stories they’re telling aren’t just for Las Vegas—they’re for any media team trying to understand what a modern, cost-efficient, deeply integrated workflow actually looks like in practice.
Here’s a look at each partner, the problem they solve, and why it matters.
Imaginario AI: From Archive to Action
Presenter: Jose Puga, CEO and Co-Founder, Imaginario AI
Most video archives are passive. Content sits in storage, cataloged by someone who had time to do it years ago, effectively invisible to the people who could use it today. Imaginario AI flips that model.
Jose Puga’s session, “From Archive to Action: How AI Is Turning Your Video Library Into a Revenue Engine,” frames the shift from passive storage and cataloging to intelligent systems that actively surface, repurpose, and monetize content. The talk covers how marketing teams can accelerate campaigns, post-production teams can shortcut assembly, and compliance workflows can move from reactive to automated.
Imaginario is a multimodal video agentic platform that understands video in a human-like way—recognizing sounds, speech, and visual scenes without requiring time-based metadata. The platform is trusted by Warner Bros. Discovery, Sony Music, and Universal Pictures, and has won back-to-back IBC Best of Show honors in 2024 and 2025.
The Backblaze integration means content stays where it lives—no migration, no friction. As Jose puts it: “Backblaze provides our clients a scalable, reliable cloud layer that eliminates the friction of manual data transfers. Our native integration saves video teams dozens of hours by keeping content on Backblaze while unlocking high-speed AI analysis, retrieval, and repurposing in media and entertainment.”
Suite Studios: S3 Native File Streaming
Presenter: Jay Maxwell, Co-Founder & CPO, Suite Studios
Remote and distributed production teams have wrestled with the same problem for years: How do you collaborate on large media files when your team is spread across the globe? Suite’s answer is S3 Native File Streaming on Backblaze B2. The stack makes working with cloud object storage all-around easier, enabling teams to read and write data as standard objects without copying, syncing, or transferring.
Jay Maxwell’s session explores how global teams can instantly access and collaborate on large media files from anywhere—eliminating delays and accelerating production timelines. No syncing, no waiting, no workarounds. Just files that behave the way you need them to, wherever your team happens to be.
TwelveLabs: Unlocking Archive Value with Video AI
Presenter: Jordan Woods, Senior Solutions Architect, TwelveLabs
There’s a pattern across media organizations of all sizes: years of valuable archived content sitting effectively invisible because manual cataloging doesn’t scale. TwelveLabs makes that content searchable and monetizable.
Jordan Woods’ session, “Unlocking Archive Value with TwelveLabs Video Intelligence,” shows how pairing Backblaze’s cost-efficient storage with TwelveLabs’ video AI gives organizations a practical path to turn dormant archives into searchable, monetizable assets.
As Danny Nicolopoulos, Head of Strategic Partnerships at TwelveLabs, explains: “Media companies are sitting on years of valuable archived content that’s effectively invisible because manual cataloging doesn’t scale. Pairing Backblaze’s cost-efficient storage with TwelveLabs’ video AI gives organizations a practical path to turn those dormant archives into searchable, monetizable assets.”
Tillered: Full Speed Cloud Storage Over Any Distance
Presenters: Davey Goode, Founder & Stephen Ceci, Commercial Lead, Tillered
Physics is an undefeated opponent. Move data over long distances and throughput drops—no matter how fast your storage is or how much bandwidth you have. Tillered is built to remove that distance penalty.
The session, “Backblaze B2 Accelerate with Tillered: Full Speed Cloud Storage Over Any Distance,” demonstrates how the B2 Accelerate product brings Tillered’s acceleration technology to Backblaze B2, with transfers up to 34x faster as a result. No simulations—just live transfers with real results, showing what it looks like when enterprises can move data across any distance without adding bandwidth or changing workflows.
Davey Goode founded Tillered after repeatedly running into the same issue building large-scale connectivity infrastructure: No matter how much bandwidth was available, performance collapsed over distance. This session is the solution he built.
Telestream UP.Review: Decide Faster
Presenter: Sebastian Manemann, Senior Director of Product Management, Telestream
Capture, storage, and distribution have gotten faster. Review hasn’t kept up. Proxies, downloads, duplicated files—the approval workflow often undoes the speed gains made everywhere else in the pipeline.
Sebastian Manemann’s session, “Decide Faster: Real-Time Review, QC, and Delivery with Telestream UP.Review and Backblaze B2,” demos how Telestream UP.Review enables real-time, high-resolution playback and QC directly on media stored in Backblaze B2 without moving or duplicating files.
By keeping content in Backblaze as the central storage layer, teams can review instantly, validate quality, and move to delivery faster—all while maintaining a single source of truth across the workflow. As Sebastian frames it: “When you eliminate duplication and review directly from storage, you don’t just move faster—you operate smarter.”
Qencode + Sardius: A Multi-Vendor M&E Workflow in Practice
Presenters: Murad Mordukhay, CEO, Qencode, and Jason Shore & Ari Burt, Sardius Media
This one is different from the others—it’s not a product demo; it’s a case study. Sardius Media rebuilt their media pipeline around a race model: Multiple storage providers write in parallel, and the fastest result wins.
The session breaks down how Backblaze wins approximately 80% of those races, with Qencode orchestrating the encoding layer across the pipeline. It covers what the production data actually shows, and what Sardius would do differently if they were designing the workflow from scratch today.
Qencode uses machine learning to reduce file sizes by an average of 60% without sacrificing quality. Their CEO, Murad Mordukhay, sums up the partnership plainly: “The best partnerships are when two companies solve different halves of the same problem. Backblaze handles storage with the kind of reliability and transparency that perfectly aligns with how we think about transcoding. No surprises, no lock-in, just infrastructure that earns trust by performing every single day.”
Media workflows break down not just because of bad tools, but because of coordination failures between good ones. Files don’t sync. Teams duplicate work. Availability lags behind where content actually needs to be.
Christoph Jurkuhn’s session, “The Hidden Layer: Orchestrating Media Across the Stack with HiScale and Backblaze,” shows in a live demo how HiScale orchestrates media movement across distributed environments while Backblaze B2 provides the durable, scalable storage layer underneath. Files move, sync, and become available across teams and tools without delays, duplication, or manual intervention.
“Backblaze is built for straightforward, cost-efficient storage and HiScale builds on top of that to orchestrate and process your media. It’s a natural fit for modern media workflows.”
Iconik: Control Your Content
Presenter: Jeremy Strootman, Media Workflow Consultant, Iconik
At a certain scale, the problem isn’t creating content; it’s controlling it. Files get lost, search slows to a crawl, and archives become liabilities instead of assets.
Jeremy Strootman’s session, “Control Your Content: Turning Media Chaos into Operational Advantage,” demos how Iconik and Backblaze B2 give teams operational control over their media: making content instantly searchable, accessible, and reusable across the entire workflow.
With a foundational background in storage and archiving, Jeremy has spent over two decades helping content creators maximize efficiency and productivity across the entire media lifecycle, from ingest to archive. His perspective: “Backblaze gives us the scalable foundation; Iconik gives teams control over how that content is actually used.”
ToolsOnAir: Modern Broadcast Workflows on Backblaze
Presenter: Peter Steiner, Chief Business Officer, ToolsOnAir
Peter Steiner’s session, “Record, Store, Play: Modern Broadcast Workflows on Backblaze,” brings ToolsOnAir’s deep broadcast expertise to bear on what it looks like to build a complete ingest-to-playout workflow with Backblaze B2 as the storage foundation.
ToolsOnAir has been building Apple-based broadcast solutions for over a decade, with deployments across broadcast, ingest, and storage workflows worldwide. This session is for anyone running live or near-live operations who wants to understand what a modern, cloud-native broadcast stack actually looks like in practice.
The final session tackles a problem that’s only growing: As video libraries scale into the billions of assets, compliance workflows built for smaller operations don’t hold.
Ethan Steininger’s session, “What You Miss Can Cost You: AI-Powered Media Compliance at Scale on Mixpeek and Backblaze B2,” shows how Mixpeek’s multimodal AI infrastructure platform transforms unstructured content—video, images, audio, and documents—into searchable, programmable assets through a unified API.
Before founding Mixpeek, Ethan led search at MongoDB, and today Mixpeek powers enterprise workflows across media, adtech, healthcare, and brand safety, with core technology spanning feature extraction, multimodal retrieval, and a custom-built distributed vector store engineered for billion-scale workloads.
The Bigger Picture
Ten companies, one through-line: storage that integrates cleanly across the entire media stack changes what’s possible. As I put it in my article for Post Perspective:
What we are seeing is a broader realization that infrastructure decisions directly shape how teams build and operate. When pricing models penalize access or iteration, teams naturally limit how often they experiment or how much data they retain. That has a direct impact on product velocity and long-term value creation.
Backblaze didn’t have to react to this shift; it’s how we have always approached the market. Our cost model removes barriers like egress and transaction fees so teams can operate freely. That allows media organizations to focus on where value is actually created—whether that is content, audience engagement, or new AI-driven capabilities—while still maintaining craft excellence.
When your foundation is cost-efficient, S3-compatible, and built for reliability at scale, every tool in the ecosystem above it gets to do its best work. That’s what we mean when we talk about “building the future of media workflows”—not just that Backblaze stores your files, but that it enables the ecosystem built on top of it.
Join Us at NAB Show 2026
We’d love to show you around. Whether you want to catch one of the in-booth presentations, sit down for a workflow consultation, or talk through your specific storage and integration challenges, our team will be on-site all week.
AWS Elastic Beanstalk simplifies the process of deploying and scaling web applications. You upload your code, and Elastic Beanstalk handles capacity provisioning, load balancing, auto scaling, and application health monitoring.
Elastic Beanstalk now offers AI Analysis to help troubleshoot environment health issues. When you request an analysis, Elastic Beanstalk triggers a script on the Amazon EC2 instance in your environment. The script collects environment events, health data, and instance logs, sends them to Amazon Bedrock for analysis, and uploads the results to Amazon S3. The result is a set of step-by-step troubleshooting recommendations tailored to your environment’s specific issues, helping you reduce mean time to resolution (MTTR).
In the Elastic Beanstalk console, the AI Analysis button appears on the environment overview page when your environment’s health status changes to Warning, Degraded, or Severe. AI analysis is also accessible from the logs page in the console, the AWS CLI, or the EB CLI.
Prerequisites
Before getting started, ensure that you have the following:
An AWS account with access to AWS Elastic Beanstalk and Amazon Bedrock.
A supported Elastic Beanstalk platform version – AI analysis is available on Amazon Linux 2 and AL2023 based platform versions released on or after February 16, 2026. Update your environment to a supported platform version if needed.
Instance profile with required permissions – The managed policies AWSElasticBeanstalkWebTier, AWSElasticBeanstalkWorkerTier, and AWSElasticBeanstalkMulticontainerDocker now include the necessary permissions for AI analysis. Attach one or more of these managed policies to your environment’s instance profile based on your environment tier. If you use a custom instance profile, ensure it includes the following permissions:
bedrock:InvokeModel
bedrock:ListFoundationModels
elasticbeanstalk:DescribeEvents
elasticbeanstalk:DescribeEnvironmentHealth
AWS CLI installed and configured with appropriate permissions. See Installing the AWS CLI.
Anthropic use case details – AI analysis uses Anthropic Claude models through Amazon Bedrock. Anthropic requires you to submit a one-time use case details form before you can invoke their models. To submit this form, select an Anthropic model from the model catalog in the Amazon Bedrock console, or call the PutUseCaseForModelAccess API. You only need to do this once per AWS account. If you submit the form from the AWS Organizations management account, it automatically covers member accounts in the organization. For more information, see Access Amazon Bedrock foundation models.
GovCloud Regions – If you are using AWS GovCloud (US) Regions, you must enable access to the latest Anthropic Claude Sonnet and/or Opus model in Amazon Bedrock before using AI analysis. For instructions on enabling model access in GovCloud Regions, see Manage access to Amazon Bedrock foundation models. For information about the latest available Anthropic Claude Sonnet and/or Opus model, see Supported Regions and models for inference profiles.
Solution Overview
In the following sections, we demonstrate how to use AI Analysis to diagnose a Node.js application that fails after a deployment.
Create a working environment: Deploy a Node.js application to Elastic Beanstalk using the code snippets provided below.
Break the environment: Update the application with code that requires missing environment variables. This causes the environment health status to transition to Degraded.
Use AI Analysis: Request an AI Analysis from the Elastic Beanstalk console or the AWS CLI to identify the root cause of the health degradation.
Apply the fix and verify: Apply the recommendations generated by AI Analysis and confirm that the environment health returns to Ok.
The following figure shows how AI Analysis works:
Figure 1 – AI Analysis architecture
You initiate a request through the Elastic Beanstalk console (AI Analysis button) or the AWS CLI (RequestEnvironmentInfo API with InfoType set to “analyze”).
Elastic Beanstalk collects environment data, analyzes it using Amazon Bedrock (a fully managed service that provides access to foundation models through API), and stores the results in Amazon S3.
Follow the steps below to set up the sample application, break it, troubleshoot with AI Analysis, and restore the environment to a healthy state.
To try this feature, open your terminal and follow the steps below to create a sample Elastic Beanstalk environment. First, set the following variables. Replace the values with your own unique S3 bucket name and the latest Node.js solution stack for your region. To find the latest solution stack, run aws elasticbeanstalk list-available-solution-stacks.
S3_BUCKET="your-unique-bucket-name"

SOLUTION_STACK_NAME="64bit Amazon Linux 2023 v6.9.0 running Node.js 22"
Setting up the application
We use two versions of a simple Node.js application. The first version (v1-working) is a basic HTTP server that responds to requests successfully. The second version (v2-broken) introduces a dependency on environment variables that are not configured in the Elastic Beanstalk environment, simulating a common deployment issue.
Create a project directory:
mkdir test-app && cd test-app
Create the working application file (v1-working):
cat << 'EOF' > workingapp.js
const http = require('http');

const server = http.createServer((req, res) => {
    res.writeHead(200, { 'Content-Type': 'application/json' });
    res.end(JSON.stringify({ status: 'healthy', message: 'App is running' }));
});

const port = process.env.PORT || 8080;
server.listen(port, () => {
    console.log(`Server running on port ${port}`);
});
EOF
Figure 3 – Environment health showing Degraded (Red) status with the AI Analysis button visible
Step 3: Use AI Analysis
Request AI analysis from the AWS CLI or the Elastic Beanstalk console. Both methods produce the same results. The CLI approach is useful for automation and scripting, while the console provides a visual workflow where you can view results directly on the environment page. We’ll cover both options below.
Figure 4 – AI analysis output retrieved via AWS CLI
Using the Elastic Beanstalk console
When your environment’s health status is Warning, Degraded, or Severe, the AI Analysis button appears in the environment overview section of the Elastic Beanstalk console.
Navigate to the Elastic Beanstalk console.
Select your environment (test-app-env).
On the environment overview page, locate the AI Analysis button that appears when the health status indicates an issue.
Choose AI Analysis to initiate the analysis.
Video 1 – Requesting AI analysis from the Elastic Beanstalk console
If you want to restart the analysis workflow, you can click on the Reanalyze button to start a new analysis.
Step 4: Apply the fix and verify
The AI analysis identified that the application crashes because the environment does not have three required environment variables configured: TEST_VARIABLE_1, TEST_VARIABLE_2, and TEST_VARIABLE_3. As recommended by the AI analysis, set these environment variables to resolve the issue:
Figure 5 – Environment health restored to Ok (Green) after setting environment variables
Note: The steps in this walkthrough can also be performed using the EB CLI. For more information, see the EB CLI Command Reference.
Best practices
Consider these recommendations to get the most out of AI analysis for your environments.
Use supported platform versions: Ensure your environment is running an Amazon Linux 2 or AL2023 platform version released on or after February 16, 2026. Update your platform if you don’t see the AI Analysis option.
Implement fixes incrementally: If the analysis recommends multiple actions, implement them one at a time to isolate which change resolves the issue.
Review data privacy considerations: The analysis sends environment events and logs to Amazon Bedrock running in your account. For more information about how Amazon Bedrock handles your data, see the Amazon Bedrock security documentation.
AI-powered environment analysis in AWS Elastic Beanstalk significantly reduces the time and effort required to diagnose environment health issues. Instead of manually parsing through log files and cross-referencing documentation, you can now get targeted, actionable recommendations with a click of the AI Analysis button in the console or an API call.
Whether you prefer using the Elastic Beanstalk console for visual workflows or the AWS CLI/EB CLI for scripting and automation, AI analysis provides a consistent experience that helps you quickly identify root causes and resolve issues.
OpenClaw crossed 250,000 GitHub stars in 60 days, surpassing React’s decade-long record to become the most-starred software project on GitHub. At GTC 2026, NVIDIA CEO Jensen Huang declared it “the operating system for personal AI” and told the room: “For the CEOs, the question is, what’s your OpenClaw strategy?”
At NVIDIA’s Hack for Impact hackathon at GTC, I built and watched engineers build autonomous agents on NemoClaw, OpenClaw, and Nemotron. Wildfire detection ingesting NASA satellite data. Crime pattern analysis across police jurisdictions. Energy grid anomaly forecasting.
The same architectural question surfaced in every project: agents that collect and generate data at scale need a deliberate strategy for archiving, retaining, and surfacing that data. Without one, agent-produced artifacts become dark data, generated but inaccessible, unversioned, and invisible to the rest of the organization. That question only gets more consequential in production.
Beyond NemoClaw’s runtime governance: Architecting for data persistence
NVIDIA’s NemoClaw wraps OpenClaw with security through OpenShell, a runtime that sandboxes each agent at the kernel level. Network requests, file access, and inference calls are governed by declarative YAML policy, enforced outside the agent’s process so the agent itself can never override them.
OpenClaw agents create workspace files (SOUL.md, USER.md, IDENTITY.md) that define the agent’s personality, preferences, and behavioral context. Inside a NemoClaw sandbox, this state lives in a Kubernetes Persistent Volume Claim inside an embedded K3s cluster, and the community is already asking for better backup and restore workflows on the NemoClaw GitHub repo.
At fleet scale, with dozens of agents each maintaining persistent memory, conversation history, and skill artifacts, a durable storage layer beneath the runtime is what keeps agent state from becoming disposable. What that layer looks like depends on the type of data your agents produce.
The agentic data layer
Two categories of data define the storage requirements for autonomous agents.
Operational artifacts
Autonomous agents generate reports, analyses, transformed datasets, alerts, and increasingly, multimodal outputs like processed video, audio, and images. Inside NemoClaw’s sandbox, filesystem access is confined to /sandbox and /tmp, both ephemeral by design.
Cloud storage decouples the artifact from the runtime, enables scoped access via URLs, and plugs into every major orchestration framework. Bucket-level permissions and scoped application keys extend governance into the storage layer, so each agent or agent class gets write access only to its designated output path.
Lineage matters here too: Each artifact should trace back to which agent, model, inputs, and policy produced it. Our GTC project, FireWatch, used Backblaze B2 exactly this way, uploading wildfire risk reports with a bucket-scoped key, generating shareable URLs, and embedding them directly in stakeholder alert emails.
State and compliance data
Agent memory, skill artifacts, and audit logs from policy decisions all require durable, long-term retention. NemoClaw’s privacy router splits inference between local and cloud models based on policy, generating routing metadata that compliance teams will want to retain and query. Cloud storage brings high durability, append-only immutability for audit trails, and lifecycle policies for tiered retention as data ages.
We built an open source OpenClaw plugin (openclaw-b2-backup) around this: Encrypted snapshots of agent config, memory, and sessions pushed to B2 on a daily cron, before compaction events, and on gateway shutdown. Three fields to configure, rollback from chat, one-command migration to a new machine.
The agent landscape is expanding. The storage pattern is consistent.
The open-source, autonomous AI agent ecosystem now spans at least 16 variants, each optimized for a different deployment context: NanoClaw for container-isolated security, ZeroClaw for edge deployment in a 3.4MB Rust binary, IronClaw for regulated industries through Trusted Execution Environments, managed platforms like ClawCloud and Maxclaw, and Qwen-Agent from Alibaba for the Chinese developer ecosystem.
Whether self-hosted or managed, all of them produce artifacts that need to persist beyond the runtime. Teams building autonomous agents for their organizations will need durable output sharing, state backup, and cross-agent data access regardless of which runtime they choose.
What enterprise AI leaders should build toward
Architect your agent data orchestration on cloud storage. As organizations scale from initial agent deployments to multi-team production workloads, data volume grows with every agent added, every week they run, and every modality they process. Agents gather, generate, and transform data continuously. Cloud storage gives you a durable layer for managing that lifecycle: ingestion and collection, versioned outputs, long-term archival, lifecycle policies for retention, and portability across agent platforms as your organization’s runtime choices evolve. Establishing this now, while the ecosystem is still forming, is the strategic move.
Automate agent state backup as part of your deployment standard. Agents building context across customer data, internal systems, and team workflows for weeks carry real operational value. Automated workspace snapshots protect that investment, create a disaster recovery path, and enable migration across environments.
Design for lineage and audit from day one. Policy decisions, tool invocations, inference routing, and multimodal processing chains all generate metadata. For enterprises operating under SOC 2, HIPAA, or GDPR, storing lineage and audit data alongside your artifacts in cloud storage means your compliance posture is ready before the audit, not after.
NemoClaw brought governance to the agentic stack. If your organization is deploying autonomous agents today, data orchestration and lineage are your next architectural decisions. Get them right early, and your agents scale with durable state, shareable outputs, and auditable history from day one.
I may have just automated myself into a completely different job…
This is a familiar pattern among software engineers, who often, through inspiration, frustration, or sometimes even laziness, build systems to remove toil and focus on more creative work. We then end up owning and maintaining those systems, unlocking that automated goodness for the rest of those around us.
As an AI researcher, I recently took this beyond what was previously possible and have automated away my intellectual toil. And now I find myself maintaining this tool to enable all my peers on the Copilot Applied Science team to do the same.
During this process, I learned a lot about how to effectively create and collaborate using GitHub Copilot. Applying these learnings has unlocked an incredibly fast development loop for myself as well as enabled my team mates to build solutions to fit their needs.
Before I get into explaining how I made this possible, let me set the stage for what spawned this project so you better understand the scope of what you can do with GitHub Copilot.
The impetus
A large part of my job involves analyzing coding agent performance as measured against standardized evaluation benchmarks, like TerminalBench2 or SWEBench-Pro. This often involves poring through tons of what are called trajectories, which are essentially lists of the thought processes and actions agents take while performing tasks.
Each task in an evaluation dataset produces its own trajectory, showing how the agent attempted to solve that task. These trajectories are often .json files with hundreds of lines of code. Multiply that over dozens of tasks in a benchmark set and again over the many benchmark runs needing analysis on any given day, and we’re talking hundreds of thousands of lines of code to analyze.
It’s an impossible task to do alone, so I would typically turn to AI to help. When analyzing new benchmark runs, I found that I kept repeating the same loop: I used GitHub Copilot to surface patterns in the trajectories then investigated them myself—reducing the number of lines of code I had to read from hundreds of thousands to a few hundred.
However, the engineer in me saw this repetitive task and said, “I want to automate that.” Agents provide us with the means to automate this kind of intellectual work, and thus eval-agents was born.
The plan
Engineering and science teams work better together. That was my guiding principle as I set about solving this new challenge.
Thus, I approached the design and implementation strategy of this project with a couple of goals in mind:
Make these agents easy to share and use
Make it easy to author new agents
Make coding agents the primary vehicle for contributions
Bullets one and two are in GitHub’s lifeblood and are values and skills I’ve gained throughout my career, especially during my stint as an OSS maintainer on the GitHub CLI.
However, goal three shaped the project the most. I noticed that when I set GitHub Copilot up to help me build the tool effectively, it also made the project easier to use and collaborate on. That experience taught me a few key lessons, which ultimately helped push the first and second goals forward in ways I didn’t expect.
Making coding agents your primary contributor
I’ll start by describing my agentic coding setup:
Coding agent: Copilot CLI
Model used: Claude Opus 4.6
IDE: VSCode
It’s also noteworthy that I leveraged the Copilot SDK to accelerate agent creation, which is powered under the hood by the Copilot CLI. This gave me access to existing tools and MCP servers, a way to register new tools and skills, and a whole bunch of other agentic goodness out of the box that I didn’t have to reinvent myself.
With that out of the way, I could streamline the whole development process very quickly by following a few core principles:
Prompting strategies: agents work best when you’re conversational, verbose, and when you leverage planning modes before agent modes.
Architectural strategies: refactor often, update docs often, clean up often.
Iteration strategies: “trust but verify” is now “blame process, not agents.”
Uncovering and following these strategies led to an incredible phenomenon: adding new agents and features was fast and easy. We had five folks jump into the project for the first time, and we created a total of 11 new agents, four new skills, and the concept of eval-agent workflows (think scientist streams of reasoning) in less than three days. That amounted to a change of +28,858/-2,884 lines of code across 345 files.
Holy crap!
Below, I’ll go into detail about these three principles and how they enabled this amazing feat of collaboration and innovation.
Prompting strategies
We know that AI coding agents are really good at solving well-scoped problems but need handholding for the more complex problems you’d only entrust to your more senior engineers.
So, if you want your agent to act like an engineer, treat it like one. Guide its thinking, over-explain your assumptions, and leverage its research speed to plan before jumping into changes. I found it far more effective to put some stream-of-consciousness musings about a problem I was chewing on into a prompt and working with Copilot in planning mode than to give it a terse problem statement or solution.
Here’s an example of a prompt I wrote to add more robust regression tests to the tool:
> /plan I've recently observed Copilot happily updating tests to fit its new paradigms even though those tests shouldn't be updated. How can I create a reserved test space that Copilot can't touch or must reserve to protect against regressions?
This resulted in a back and forth that ultimately led to a series of guardrails akin to contract testing that can only be updated by humans. I had an idea of what I wanted, and through conversation, Copilot helped me get to the right solution.
It turns out that the things that make human engineers the most effective at doing their jobs are the same things that make these agents effective at doing theirs.
Architectural strategies
Engineers, rejoice! Remember all those refactors you wanted to do to make the codebase more readable, the tests you never had time to write, and the docs you wish had existed when you onboarded? They’re now the most important thing you can be working on when building an agent-first repository.
Gone are the days where deprioritizing this work over new feature work was necessary, because delivering features with Copilot becomes trivial when you have a well-maintained, agent-first project.
I’ve spent most of my time on this project refactoring names and file structures, documenting new features or patterns, and adding test cases for problems that I’ve uncovered as I go. I’ve even spent a few cycles cleaning up the dead code that the agents (like your junior engineers) may have missed while implementing all these new features and changes.
This work makes it easy for Copilot to navigate the codebase and understand the patterns, just like it would for any other engineer.
I can even ask, “Knowing what I know now, how would I design this differently?” And I can then justify actually going back and rearchitecting the whole project (with the help of Copilot, of course).
It’s a dream come true!
And this leads me to my last bit of guidance.
Iteration strategies
As agents and models have improved, I have moved from a “trust but verify” mindset to one that is more trusting than doubtful. This mirrors how the industry treats human teams: “blame process, not people.” It’s how the most effective teams operate, because people make mistakes, so we build systems around that reality.
This idea of blameless culture provides psychological safety for teams to iterate and innovate, knowing that they won’t be blamed if they make a mistake. The core principle is that we implement processes and guardrails to protect against mistakes, and if a mistake does happen, we learn from it and introduce new processes and guardrails so that our teams won’t make the same mistake again.
Applying this same philosophy to agent-driven development has been fundamental to unlocking this incredibly rapid iteration pipeline. That means we add processes and guardrails to help prevent the agent from making mistakes, but when it does make a mistake, we add additional guardrails and processes—like more robust tests and better prompts—so the agent can’t make the same mistake again. Taking this one step further means that practicing good CI/CD principles is a must.
Practices like strict typing ensure the agent conforms to interfaces. Robust linters impose implementation rules on the agent that keep it following good patterns and practices. And integration, end-to-end, and contract tests—which can be expensive to build manually—become much cheaper to implement with agent assistance, while giving you confidence that new changes don’t break existing features.
When Copilot has these tools available in its development loop, it can check its own work. You’re setting it up for success, much in the same way you’d set up a junior engineer for success in your project.
Putting it all together
Here’s what all this means for your development loop when you’ve got your codebase set up for agent-driven development:
Plan a new feature with Copilot using /plan.
Iterate on the plan.
Ensure that testing is included in the plan.
Ensure that docs updates are included in the plan and done before code is implemented. These can serve as additional guidelines that live beside your plan.
Let Copilot implement the feature on /autopilot.
Prompt Copilot to initiate a review loop with the Copilot Code Review agent. For me, it’s often something like: request Copilot Code Review, wait for the review to finish, address any relevant comments, and then re-request review. Continue this loop until there are no more relevant comments.
Human review. This is where I enforce the patterns I discussed in the previous sections.
Additionally, outside of your feature loop, be sure you’re prompting Copilot early and often with the following:
/plan Review the code for any missing tests, any tests that may be broken, and dead code
/plan Review the code for any duplication or opportunities for abstraction
/plan Review the documentation and code to identify any documentation gaps. Be sure to update the copilot-instructions.md to reflect any relevant changes
I have these run automatically once a week, but I often find myself running them throughout the week as new features and fixes go in to maintain my agent-driven development environment.
Take this with you
What started as a frustration with an impossibly repetitive analysis task turned into something far more interesting: a new way of thinking about how we build software, how we collaborate, and how we grow as engineers.
Building agents with a coding agent-first mindset has fundamentally changed how I work. It’s not just about the automation wins—though watching four scientists ship 11 agents, four skills, and a brand-new concept in under three days is nothing short of remarkable. It’s about what this style of development forces you to prioritize: clean architecture, thorough documentation, meaningful tests, and thoughtful design—the things we always knew mattered but never had time for.
The analogy to a junior engineer keeps proving itself out. You onboard them well, give them clear context, build guardrails so their mistakes don’t become disasters, and then trust them to grow. If something goes wrong, you blame the process. Not the agent. If there’s one thing I want you to take away from this, it’s that the skills that make you a great engineer and a great teammate are the same skills that make you great at building with Copilot. The technology is new. The principles aren’t.
So go clean up that codebase, write that documentation you’ve been putting off, and start treating your Copilot like the newest member of your team. You might just automate yourself into the most interesting work of your career.
Modern infrastructure teams increasingly interact with their systems through automation and AI-assisted tooling. Terminal-native agents like Claude Code are beginning to act less like chatbots and more like operational collaborators, able to inspect environments, run commands, and help maintain infrastructure.
Today we’re releasing a new open-source tool designed for that workflow: the Backblaze B2 Cloud Storage Skill for Claude.
This GitHub repository provides a structured skill that allows Claude-based agents to safely interact with Backblaze B2 Cloud Storage through the B2 CLI. Instead of manually running storage audits, searching buckets, or reviewing lifecycle rules, you can ask an AI assistant to help perform those tasks directly in your development environment.
The result is simple and powerful: An open source natural language interface for inspecting and managing B2 Cloud Storage, built with guardrails.
What is the B2 Cloud Storage Skill for Claude?
The B2 Cloud Storage Skill for Claude is an open-source repository that enables AI-assisted management of B2 buckets using the official Backblaze B2 CLI.
The project includes three primary components:
1. A Claude Skill Definition
The skill file provides structured instructions that teach Claude how to safely interact with B2 Cloud Storage. It defines the commands the assistant can use, outlines safe operational practices, and establishes restrictions around sensitive data and destructive actions.
This allows Claude to perform storage operations while respecting operational safeguards.
2. A Storage Audit Script
The repository includes a Python script that analyzes the contents of a bucket and produces a structured report. The audit can:
Summarize storage usage by directory prefix
Analyze file types and extensions
Identify files older than 90 days
Flag objects larger than 100MB
Detect potential duplicates based on filename
The result is a quick operational snapshot of a bucket’s structure and usage patterns—useful for cost awareness, lifecycle planning, and housekeeping.
The skill supports per-project configuration through a .claude/b2-config.json file. This allows developers to specify a default bucket, a working prefix, or a project-specific credential file.
In practice, that means different repositories or services can point to different storage buckets without changing global CLI configuration.
How to use it
The skill is designed to work in environments where Claude Code or similar agent-based developer tools can execute terminal commands.
A typical workflow looks like this:
Install and configure the B2 CLI.
Authorize the CLI with a B2 application key.
Add the skill repository to your Claude environment.
Optionally configure a project-specific bucket.
Once configured, you can ask Claude to perform storage tasks directly from your terminal.
Examples include:
Audit the contents of this bucket.
List files older than 90 days.
Show the largest objects in this prefix.
Check the bucket’s lifecycle rules.
Find duplicate filenames across directories.
Under the hood, the assistant is running standard B2 CLI commands and the included audit script. The skill simply provides the structure that allows an AI agent to use those tools correctly.
This approach keeps the operational layer transparent: Everything ultimately resolves to normal CLI commands you can run (and double check) yourself.
Why it matters
Cloud storage environments grow quietly.
Buckets accumulate logs, backups, generated assets, and intermediate files over time. Without periodic inspection, those collections can become difficult to understand or maintain.
Historically, storage audits have been manual exercises: writing scripts, exporting listings, or running ad-hoc commands.
AI-assisted tooling changes that interaction model.
Instead of constructing queries, operators can ask for insights:
Where is the storage concentrated?
Which files are stale?
Are lifecycle policies doing their job?
Are there large objects that should be archived or removed?
The B2 Cloud Storage Skill bridges the gap between AI-assisted workflows and real storage infrastructure.
Just as importantly, the repository is designed with safety in mind. The skill restricts commands that could expose credentials, requires dry-runs before deletion operations, and warns when actions could change bucket visibility.
In other words, it treats AI as an operational assistant—not an autonomous administrator.
Open source and extensible
The repository is intentionally lightweight and open.
It’s meant to serve as both a practical tool and a starting point for developers exploring how AI agents can interact with storage infrastructure.
Possible extensions include:
Automated lifecycle policy recommendations
Deeper storage analytics
Integration with monitoring pipelines
Custom audit rules for specific workloads
If you’re experimenting with AI-assisted operations—or simply want a faster way to inspect your B2 Cloud Storage—this skill provides a practical place to start.
You can explore the repository and try it yourself here:
As demand for AI infrastructure keeps climbing, a new wave of providers is proving there’s real appetite for something other than the traditional hyperscaler model. They’re moving fast, specializing deeply, and building strong businesses around the layers that matter most to their customers: GPU access, high-performance compute, AI services, and developer experience.
That momentum is real, as is the next bottleneck. For many neoclouds, the challenge is no longer just how to deliver more compute. It’s how to deliver a more complete platform without taking on all the complexity of becoming a full-stack cloud provider. And that usually brings teams to the same question: Sshould we build our own storage layer?
Key points: Why should neoclouds care about specialized storage?
Neoclouds are capturing a major market opportunity by specializing in compute, AI, and high-performance infrastructure instead of trying to replicate the hyperscaler model. But without an independent, S3 compatible storage layer, many providers run into a split-stack problem: compute lives on the neocloud while data stays in a major cloud, bringing egress fees, friction, and architectural sprawl.
Teams that decide to build storage themselves often underestimate what that really means. Whether the path is open-source software like Ceph or purpose-built hardware, the result is often the same: Slower execution, more operational burden, and less focus on the product that actually differentiates the business.
The stronger strategy is to treat storage as a specialized tech stack layer and intentionally partner to solve the need, so internal teams can stay focused on compute, AI services, and customer experience.
Backblaze gives neoclouds an S3 compatible object storage backbone that can be integrated quickly, scaled immediately, and delivered without the overhead of building and operating storage from scratch.
The real neocloud opportunity is specialization
The shift toward neoclouds is really a shift toward specialization.
For years, the default assumption in cloud infrastructure was that the winning model looked like a hyperscaler: Build the entire stack, own every layer, and expand horizontally into as many services as possible. That model produced scale, but it also produced operational sprawl, complexity, and costs that many customers are increasingly motivated to avoid.
Neoclouds are succeeding because they’re taking the opposite path. Instead of trying to be everything to everyone, they’re building best-of-breed platforms around targeted workloads and high-value services. That’s especially true in AI, where performance, cost control, and speed matter more than a long menu of loosely related products.
But the closer a neocloud gets to becoming a full platform, the more pressure it faces to solve for storage.
The split-stack problem gets expensive
Without integrated object storage, customers often end up in a split-stack architecture. They run compute on a neocloud, but keep their data parked in a major cloud provider, which creates problems quickly.
For example: Large training datasets, model checkpoints, and output artifacts have to move across environments, costs become harder to predict, egress charges start to shape architecture decisions, and performance can suffer when storage and compute are no longer designed to work together.
At that point, storage becomes a core requirement for offering a platform that feels complete, efficient, and economically viable.
So teams ask the obvious question: should we build it ourselves?
Building storage usually means building a second company inside your company
This is where the conversation often gets framed too narrowly.
On paper, the decision can look straightforward: deploy open-source software such as Ceph, or design purpose-built hardware for tighter control over performance and economics.
In reality, both paths create the same strategic problem. They pull engineering focus away from your core platform and into a long-term storage business you never actually meant to start.
That matters because storage is not just infrastructure. It is an operating discipline. It comes with its own tuning, scaling, durability trade-offs, support burden, procurement risk, migration complexity, and day-two operational entropy.
Once you build it, you own all of it.
The software trap: Ceph is open source, not low overhead
Ceph is often the default option for teams exploring S3 compatible storage because it appears flexible, proven, and relatively accessible on commodity hardware.
And to be clear, Ceph can be powerful. But there’s a big difference between deploying Ceph and running it well at scale.
In production, Ceph demands specialized expertise. Teams have to manage CRUSH maps, OSD tuning, replication behavior, rebalancing events, and the network impact that comes with those changes. Those are not occasional tasks. They are part of the ongoing operational load.
That burden grows as environments get larger and more performance-sensitive.
For AI and high-performance compute use cases, generic Ceph deployments can also become throughput bottlenecks. When storage ceilings start constraining training jobs or data-intensive workflows, the problem is no longer confined to the storage team. It starts affecting the value of your core compute offering.
And migration is rarely simple. Because data is distributed across the cluster in ways that are optimized for internal resilience, moving out of a Ceph environment can become a resource-heavy extraction exercise that introduces risk to live workloads.
So while Ceph may reduce license costs up front, it can create a much more expensive operational reality over time.
The hardware trap: more control, more rigidity
For some neocloud teams, custom storage hardware feels like the more strategic answer.
The logic is easy to understand: if storage is critical, why not optimize the hardware and software stack together and get more predictable performance?
The issue is that custom storage hardware rarely stays clean and predictable for long.
Supply chains change. Drive capacities shift. Components become harder to source consistently. Architectures designed around one hardware profile suddenly have to absorb another. This dynamic can leave teams paying for density they can’t fully use or reworking systems to accommodate equipment that wasn’t part of the original plan.
Durability management adds another layer of complexity. As systems age, parity strategies and erasure coding decisions may need to change to maintain reliability. That can reduce usable capacity, increase cost per terabyte, and trigger compute-intensive re-encoding processes at exactly the wrong time.
Then there’s the networking layer. At scale, object storage is not just disks and nodes. It also depends on a traffic management architecture capable of handling massive ingress and egress flows without introducing opaque failure points. Whether you build around open source components or buy expensive hardware appliances, you’re signing up for another category of highly specialized infrastructure work.
And all of that comes with a capital model that is harder to unwind. Hardware investments lock teams into depreciation cycles and planning assumptions that may not match where the market is headed next.
The strategic shift: own differentiation, not every layer
The most important shift here is not technical. It’s organizational.
At a certain point, the storage question becomes a question of where your best people should spend their time.
Should your engineers be tuning replication policies, planning hardware refreshes, and troubleshooting storage network behavior?
Or should they be improving the platform features your customers actually choose you for?
For most neoclouds, the answer is clear.
Their advantage comes from how well they deliver compute, how quickly they adapt to AI demand, how smooth their developer experience feels, and how effectively they help customers run modern workloads. That is where focus compounds. That is where differentiation lives.
Storage matters enormously, but that does not mean it has to be built in-house.
Storage works better as a specialized utility
The neocloud ecosystem works best when providers can connect to open, specialized layers instead of rebuilding the entire stack themselves.
When storage is treated as a utility rather than an internal R&D project, teams can move faster and stay aligned with what the business actually needs. They avoid procurement cycles, reduce operational overhead, and eliminate a category of complexity that would otherwise keep expanding over time.
Equally importantly, they can offer customers a more complete and coherent platform without forcing data to remain trapped in legacy cloud environments.
How Backblaze helps neoclouds move faster
Backblaze gives neoclouds an independent, S3-compatible object storage backbone that can plug into existing compute, AI, and container workflows without requiring a storage buildout from scratch.
That means teams can:
Integrate with existing tooling: Use a drop-in, API-compatible storage layer that works with existing workflows, SDKs, CLIs, and infrastructure tools.
Reduce operational burden: Offload the complexity of durability engineering, bit-rot protection, fleet management, and storage operations.
Avoid punitive egress economics: In Backblaze-powered and colocated partner environments, move data between compute and storage without the cost friction that often comes with major cloud architectures.
Scale immediately: Go from terabytes to exabytes without waiting on hardware procurement, deployment schedules, or expansion projects.
Keep teams focused: Direct engineering effort toward the product roadmap instead of a second internal storage program.
Backblaze also brings the underlying scale and performance neoclouds need to support modern AI and data-intensive workloads, including up to 1Tbps aggregate throughput, 11 nines of annual durability, a 99.9% uptime SLA, and enterprise security and compliance capabilities.
Build what matters
Neoclouds are winning because they know where to specialize.
That focus is their strength. It is also their opportunity.
The fastest path to a stronger platform is not to recreate every layer of the cloud stack. It is to build the parts that make your business distinct, then connect them to the right partners for the rest.
Storage is too important to ignore, but it is also too easy to underestimate.
If you want to move faster, serve customers better, and keep your roadmap centered on what makes your platform valuable, don’t turn storage into a distraction.
Build what matters. Let Backblaze handle the storage.Interested in learning how Backblaze supports neocloud platforms? Explore B2 Neo or talk with our team about building a more open, AI-ready storage architecture.
For years, accessibility feedback at GitHub didn’t have a clear place to go.
Unlike typical product feedback, accessibility issues don’t belong to any single team—they cut across the entire ecosystem. For example, a screen reader user might report a broken workflow that touches navigation, authentication, and settings. A keyboard-only user might hit a trap in a shared component used across dozens of pages. A low vision user might flag a color contrast issue that affects every surface using a shared design element. No single team owns any of these problems—but every one of them blocks a real person.
These reports require coordination that our existing processes weren’t originally built for. Feedback was often scattered across backlogs, bugs lingered without owners, and users followed up to silence. Improvements were often promised for a mythical “phase two” that rarely materialized.
We knew we needed to change this. But before we could build something better, we had to lay the groundwork—centralizing scattered reports, creating templates, and triaging years of backlog. Only once we had that foundation in place could we ask: How can AI make this easier?
The answer was an internal workflow, powered by GitHub Actions, GitHub Copilot, and GitHub Models, that ensures every piece of user and customer feedback becomes a tracked, prioritized issue. When someone reports an accessibility barrier, their feedback is captured, reviewed, and followed through until it’s addressed. We didn’t want AI to replace human judgment—we wanted it to handle repetitive work so humans could focus on fixing the software.
This is how we went from chaos to a system where every piece of accessibility feedback is tracked, prioritized, and acted on—not eventually, but continuously.
Accessibility as a living system
Continuous AI for accessibility weaves inclusion into the fabric of software development. It’s not a single product or a one-time audit—it’s a living methodology that combines automation, artificial intelligence, and human expertise.
This philosophy connects directly to our support for the 2025 Global Accessibility Awareness Day (GAAD) pledge: strengthening accessibility across the open source ecosystem by ensuring user and customer feedback is routed to the right teams and translated into meaningful platform improvements.
The most important breakthroughs rarely come from code scanners—they come from listening to real people. But listening at scale is hard, which is why we needed technology to help amplify those voices. We built a feedback workflow that functions less like a static ticketing system and more like a dynamic engine—leveraging GitHub products to clarify, structure, and track user and customer feedback, turning it into implementation-ready solutions.
Designing for people first
Before jumping into solutions, we stepped back to understand who this system needed to serve:
Issue submitters: Community managers, support agents, and sales reps submit issues on behalf of users and customers. They aren’t always accessibility experts, so they need a system that guides them and teaches accessibility concepts in the flow of work.
Accessibility and service teams: Engineers and designers responsible for fixes need structured, actionable data—reproducible steps, WCAG mapping, severity scores, and clear ownership.
Program and product managers: Leadership needs visibility into pain points by category, trends, and progress over time to allocate resources strategically.
With these personas in mind, we knew we wanted to 1) treat feedback as data flowing through a pipeline and 2) build a system able to evolve with us.
How feedback flows
With that foundation set, we built an architecture around an event-driven pattern, where each step triggers a GitHub Action that orchestrates what comes next—ensuring consistent handling no matter where the feedback originates. We built this system largely by hand starting in mid-2024. Today, tools like Agentic Workflows let you create GitHub Actions using natural language—meaning this kind of system could be built in a fraction of the time.
The workflow reacts to key events: Issue creation launches GitHub Copilot analysis via the GitHub Models API, status changes initiate hand-offs between teams, and resolution triggers submitter follow-up with the user. Every Action can also be triggered manually or re-run as needed—automation covers the common path, while humans can step in at any point.
Feedback isn’t just captured—it continuously flows through the right channels, providing visibility, structure, and actionability at every stage.
*Click images to enlarge.
1. Actioning intake
Feedback can come from anywhere—support tickets, social media posts, email, direct outreach—but most users choose the GitHub accessibility discussion board. It’s where they can work together and build community around shared experiences. Today, 90% of the accessibility feedback flows through that single channel. Because posts are public, other users can confirm the problem, add context, or suggest workarounds—so issues often arrive with richer detail than a support ticket ever could. Regardless of the source, every piece of feedback gets acknowledged within five business days, and even feedback we can’t act on gets a response pointing to helpful resources.
When feedback requires action from internal teams, a team member manually creates a tracking issue using our custom accessibility feedback issue template. Issue templates are pre-defined forms that standardize how information is collected when opening a new issue. The template captures the initial context—what the user reported, where it came from, and which components are involved—so nothing is lost between intake and triage.
This is where automation kicks in. Creating the issue triggers a GitHub Action that engages GitHub Copilot, and a second Action adds the issue to a project board, providing a centralized view of current status, surfacing trends, and helping identify emerging needs.
2. GitHub Copilot analysis
With the tracking issue created, a GitHub Action workflow programmatically calls the GitHub Models API to analyze the report. We chose stored prompts over model fine-tuning so that anyone on the team can update the AI’s behavior through a pull request—no retraining pipeline, no specialized ML knowledge required.
We configured GitHub Copilot using custom instructions developed by our accessibility subject matter experts. Our prompt serves two roles: triage analysis, which classifies issues by WCAG violation, severity, and affected user group, and accessibility coaching, where GitHub Copilot acts as a subject-matter expert to help teams write and review accessible code.
These instruction files point to our accessibility policies, component library, and internal documentation that details how we interpret and apply WCAG success criteria. When our standards evolve, the team updates the markdown and instruction files via pull request—the AI’s behavior changes with the next run, not the next training cycle. For a detailed walkthrough of this approach, see our guide on optimizing GitHub Copilot custom instructions for accessibility.
The automation works in two steps. First, an Action fires on issue creation and triggers GitHub Copilot to analyze the report. GitHub Copilot populates approximately 80% of the issue’s metadata automatically—over 40 data points including issue type, user segment, original source, affected components, and enough context to understand the user’s experience. The remaining 20% requires manual input from the team member. GitHub Copilot then posts a comment on the issue containing:
A summary of the problem and user impact
Suggested WCAG success criteria for potential violations
Severity level (sev1 through sev4, where sev1 is critical)
Impacted user groups (screen reader users, keyboard users, low vision users, etc.)
Recommended team assignment (design, engineering, or both)
A checklist of low-barrier accessibility tests so the submitter can verify the issue
Then a second Action fires on that comment, parses the response, applies labels based on the severity GitHub Copilot assigned, updates the issue’s status on the project board, and assigns it to the submitter for review.
If GitHub Copilot’s analysis seems off, anyone can flag it by opening an issue describing what it got wrong and what it should have said—feeding directly into our continuous improvement process.
3. Submitter review
Before we act on GitHub Copilot’s recommendations, two layers of review happen—starting with the issue submitter.
The submitter attempts to replicate the problem the user reported. The checklist GitHub Copilot provides in its comment guides our community managers, support agents, and sales reps through expert-level testing procedures—no accessibility expertise required. Each item includes plain-language explanations, step-by-step instructions, and links to tools and documentation.
Example questions include:
Can you navigate the page using only a keyboard? Press “Tab” to move through interactive elements. Can you reach all buttons, links, and form fields? Can you see where your focus is at all times?
Do images have descriptive alt text? Right-click an image and select “Inspect” to view the markup. Does the alt attribute describe the image’s purpose, or is it a generic file name?
Are interactive elements clearly labeled? Using a screen reader, navigate to a button or link. Is its purpose announced clearly? Alternatively, review the accessibility tree in your browser’s developer tools to inspect how elements are exposed to assistive technologies.
If the submitter can replicate the problem, they mark the issue as reviewed, which triggers the next GitHub Action. If they can’t reproduce it, they reach out to the user for more details. Once new information arrives, the submitter can re-run the GitHub Copilot analysis—either by manually triggering the Action from the Actions tab or by removing and re-adding the relevant label to kick it off automatically. AI provides the draft, but humans provide the verification.
4. Accessibility team review
Once the submitter marks the issue as reviewed, a GitHub Action updates its status on the workflow project board and adds it to a separate accessibility first responder board. This alerts the accessibility team—engineers, designers, champions, testing vendors, and managers—that GitHub Copilot’s analysis is ready for their review.
The team validates GitHub Copilot’s analysis—checking the severity level, WCAG mapping, and category labels—and corrects anything the AI got wrong. When there’s a discrepancy, we assume the human is correct. We log these corrections and use them to refine the prompt files, improving future accuracy.
Once validated, the team determines the resolution approach:
Documentation or settings update: Provide the solution directly to the user.
Code fix by the accessibility team: Create a pull request directly.
Service team needed: Assign the issue to the appropriate service team and track it through resolution.
With a path forward set, the team marks the issue as triaged. An Action then reassigns it to the submitter, who communicates the plan to the user—letting them know what’s being done and what to expect.
5. Linking to audits
As part of the review process, the team connects user and customer feedback to our formal accessibility audit system.
Roughly 75–80% of the time, reported issues correspond to something we already know about from internal audits. Instead of creating duplicates, we find the existing internal audit issue and add a customer-reported label. This lets us prioritize based on real-world impact—a sev2 issue might technically be less critical than a sev1, but if multiple users are reporting it, we bump up its priority.
If the feedback reveals something new, we create a new audit issue and link it to the tracking issue.
6. Closing the loop
This is the most critical step for trust. Users who take the time to report accessibility barriers deserve to know their feedback led to action.
Once a resolution path is set, the submitter reaches out to the original user to let them know the plan—what’s being fixed, and what to expect. When the fix ships, the submitter follows up again and asks the user to test it. Because most issues originate from the community discussion board, we post confirmations there for everyone to see.
If the user confirms the fix works, we close the tracking issue. If the fix doesn’t fully address the problem, the submitter gathers more details and the process loops back to the accessibility team review. We don’t close issues until the user confirms the fix works for them.
7. Continuous improvement
The workflow doesn’t end when an issue closes—it feeds back into itself.
When submitters or accessibility team members spot inaccuracies in GitHub Copilot’s output, they open a new issue requesting a review of the results. Every GitHub Copilot analysis comment includes a link to create this issue at the bottom, so the feedback loop is built into the workflow itself. The team reviews the inaccuracy, and the correction becomes a pull request to the custom instruction and prompt files described earlier.
We also automate the integration of new accessibility guidance. A separate GitHub Action scans our internal accessibility guide repository weekly and incorporates changes into GitHub Copilot’s custom instructions automatically.
The goal isn’t perfection—it’s continuous improvement. Each quarter, we review accuracy metrics and refine our instructions. These reviews feed into quarterly and fiscal year reports that track resolution times, WCAG failure patterns, and feedback volume trends—giving leadership visibility into both progress and persistent gaps. The system gets smarter over time, and now we have the data to show it.
Impact in numbers
A year ago, nearly half of accessibility feedback sat unresolved for over 300 days. Today, that backlog isn’t just smaller—it’s gone. And the improvements don’t stop there.
89% of issues now close within 90 days (up from 21%)
62% reduction in average resolution time (118 days → 45 days)
70% reduction in manual administrative time
1,150% increase in issues resolved within 30 days (4 → 50 year-over-year)
50% reduction in critical sev1 issues
100% of issues closed within 60 days in our most recent quarter
We track this through automated weekly and quarterly reports generated by GitHub Actions—surfacing which WCAG criteria fail most often and how resolution times trend over time.
Beyond the numbers
A user named James emailed us to report that the GitHub Copilot CLI was inaccessible. Decorative formatting created noise for screen readers, and interactive elements were impossible to navigate.
A team member created a tracking issue. Within moments, GitHub Copilot analyzed the report—mapping James’s description to specific technical concepts, linking to internal documentation, and providing reproduction steps so the submitter could experience the product exactly as James did.
With that context, the team member realized our engineering team had already shipped accessible CLI updates earlier in the year—James simply wasn’t aware.
They replied immediately. His response? “Thanks for pointing out the –screen-reader mode, which I think will help massively.”
Because the AI workflow identified the problem correctly, we turned a frustration into a resolution in hours.
But the most rewarding result isn’t the speed—it’s the feedback from users. Not just that we responded, but that the fixes actually worked for them:
“Huge thanks to the team for updating the contributions graph in the high contrast theme. The addition of borders around the grid edges is a small but meaningful improvement. Keep it up!”
“Let’s say you want to create several labels for your GitHub-powered workflow: bug, enhancement, dependency updates… But what if you are blind? Before you had only hex codes randomly thrown at you… now it’s fixed, and those colors have meaningful English names. Well done, GitHub!”
“This may not be very professional but I literally just screamed! This fix has actually made my day… Before this I was getting my wife to manage the GitHub issues but now I can actually navigate them by myself! It means a lot that I can now be a bit more independent so thank you again.”
That independence is the point. Every workflow, every automation, every review—it all exists so moments like these are the expectation, not the exception.
The bigger picture
Stories like these remind us why the foundation matters. Design annotations, code scanners, accessibility champions, and testing with people with disabilities—these aren’t replaced by AI. They are what make AI-assisted workflows effective. Without that human foundation, AI is just a faster way to miss the point.
We’re still learning, and the system is still evolving. But every piece of feedback teaches us something, and that knowledge now flows continuously back to our team, our users, and the tools we build.
If you maintain a repository—whether it’s a massive enterprise project or a weekend open-source library—you can build this kind of system today. Start small. Create an issue template for accessibility. Add a .github/copilot-instructions.md file with your team’s accessibility standards. Let AI handle the triage and formatting so your team can focus on what really matters: writing more inclusive code.
And if you hit an accessibility barrier while using GitHub, please share your feedback. It won’t disappear into a backlog. We’re listening—and now we have the system to follow through.
When AWS’s us-east-1 region went down for over 15 hours on October 20, 2025, the cascade of failures exposed just how fragile the internet’s infrastructure has become. Major services like Discord, Slack, Atlassian, and parts of Netflix suddenly went dark. These companies weren’t all direct AWS customers, but the vendors they relied on were. Authentication systems failed. CDNs stopped responding. Monitoring tools went blind. Companies that thought they’d diversified their cloud strategy discovered their backups were just as offline as their primary systems.
The solutions organizations thought they’d implemented, like multi-cloud deployments, redundant architectures, and disaster recovery plans, often provide little more than the illusion of protection.
The illusion of diversification
A company migrates its primary compute workload from AWS to Google Cloud or Azure, checks the “multi-cloud” box, and considers the job done. But authentication still runs through AWS Cognito. The CDN is CloudFront. Monitoring lives in CloudWatch. DNS resolution depends on Route 53. When AWS’s control plane fails, the entire architecture collapses regardless of where the compute actually runs.
ThousandEyes documented exactly this pattern during the October 2025 AWS outage. Packet loss and routing instability affected direct AWS customers and cascaded into dependent networks and services that appeared independent on paper, but shared the same regional infrastructure under the hood. Organizations often discover these dependencies only during outages, when it’s too late to do anything about them.
Why concentration accelerates despite known risks
Everyone knows concentration is dangerous, yet it keeps accelerating. The same forces that make hyperscalers attractive—operational simplicity, unified tooling, procurement efficiency—concentrate risk faster than diversification efforts can mitigate it.
Teams often adopt unified tooling for operational simplicity, which reduces integration costs and builds vendor-specific expertise. As more systems integrate with that tooling, switching costs increase. Eventually, the platform becomes the default rather than a choice. Each new service added to the stack makes it harder to leave.
Hyperscaler architecture isn’t just a risk, it’s a cost
Amplify’s AWS egress fees were growing to 10x their storage costs as customers downloaded more datasets. CTO Ameya Pathare evaluated Azure, Google Cloud, Digital Ocean, and Wasabi before building a modular architecture: Snowflake for data transformation and Backblaze B2 for staging, with outputs available across Google BigQuery and Tableau.
The two-week migration with zero downtime delivered 70% cost savings that compound with every download. When individual providers experience issues, customers maintain access through alternative paths. “If we had stayed on AWS, we’d have needed to change our pricing and pass on those egress fees to the customer,” Pathare says.
Diversification efforts lag behind because they require deliberate architectural decisions that run counter to operational efficiency. According to the CNCF’s 2025 State of Cloud report, 30% of organizations deploy to hybrid cloud environments and 23% to multi-cloud. That sounds encouraging until you look at what they’re actually distributing. Most organizations spread their compute across providers while consolidating authentication, orchestration, and monitoring with a single vendor. Deployment location differs from dependency structure.
Gartner projects that 90% of organizations will adopt hybrid cloud approaches by 2027. But without intentional failure domain separation, these deployments maintain the same concentrated dependencies they’re meant to avoid.
Why untested recovery paths fail
Most organizations treat failover mechanisms like insurance policies: pay the premium, file the documentation, and hope you never need to use it. Then an outage hits and they discover their recovery paths don’t actually work.
Google’s SRE team analyzed this pattern in their twenty-year retrospective: “Recovery mechanisms that are not tested before an incident routinely fail when they are needed most.” Configuration drift makes systems behave differently in production than they did in testing. Teams encounter unfamiliar tooling under pressure. Communication systems fail because they rely on the same infrastructure that’s down.
Three practices separate resilient systems from brittle ones:
Explicit failure domain mapping: Document which components fail together, including indirect dependencies. During Google’s 2017 OAuth incident, teams assumed Hangouts and Meet would remain available for coordination during the recovery. Both services relied on the failing authentication system.
Continuous exercised recovery: Failover paths tested regularly rather than only during incidents. YouTube’s 2016 caching failure required risky load-shedding operations that had never been practiced outside staging environments.
Graceful degradation by design: Systems intentionally reduce functionality rather than collapse completely. Without this capability built in and tested, systems crash entirely instead of slowing down when they encounter partial failures.
Most organizations implement sophisticated monitoring and alerting but lack tested mechanisms to act on that information when infrastructure degrades.
How modular infrastructure reduces risk
Resilient architectures break infrastructure into interoperable components from specialized providers. Organizations can select compute, storage, networking, and delivery independently based on performance and reliability characteristics. A disruption in one layer no longer automatically incapacitates the entire system.
Cloudflare’s October 30, 2023 incident demonstrates what happens when this separation doesn’t exist. A deployment misconfiguration propagated across tightly coupled internal services. Workers KV became unreachable, which cascaded into failures across Pages, Access, Zero Trust, Images, and the Cloudflare Dashboard itself. Shared tooling and control systems collapsed multiple services into a single failure domain, even within a provider marketed as redundant.
Sardius Media demonstrates what modular cloud infrastructure looks like in practice. The company architected its system from inception to be cloud-agnostic, using a race algorithm that queries multiple cloud providers and CDNs for every API call and selects the fastest response. True resilience through competitive redundancy.
The data layer as a gating factor
Storage architecture determines whether all this architectural planning actually works. Can your data move when you need it to? The answer depends on whether systems can replicate and recover across providers under real-world conditions.
Control-plane access matters more than data replication. During Google Cloud’s June 2025 API misconfiguration, Gmail, Spotify, and Cloudflare went dark despite having intact data layers. Replication across availability zones provided no protection when authentication and API access failed.
Three technical barriers trap workloads in place:
Large dataset transfer costs make migration prohibitively expensive.
Proprietary vendor APIs create application lock-in that requires substantial refactoring to escape.
Unpredictable egress charges turn what was supposed to be a temporary deployment into permanent infrastructure because moving the data out costs more than leaving it there.
Storage architectures that support open APIs, predictable pricing, and cross-provider replication enable genuine mobility. Systems can replicate data across providers, recover faster from incidents through parallel data access, and maintain portable compute and delivery layers. Implementation requires mapping both direct dependencies (compute, storage, CDN) and indirect ones (managed services that converge on the same infrastructure), then assigning explicit recovery requirements to critical workloads.
From scattered clouds to a united front
The internet’s reliability challenges stem from correlated dependencies rather than cloud technology. Neocloud ecosystems make resilient architectures achievable by promoting specialization and interoperability.
Organizations can select best-of-breed providers for each infrastructure layer—compute, storage, networking, delivery—without forcing everything through a single vendor’s control plane. Open cloud storage ensures those ecosystems remain flexible under pressure, with data that can replicate across providers, portable applications that aren’t locked into proprietary APIs, and predictable costs that don’t trap workloads in place.
The result is systems that continue operating when individual providers fail. They’ve ensured that failures remain isolated rather than cascading across the entire architecture.
There’s a new open-source plugin that snapshots your OpenClaw config, memory, and sessions to B2. It’s designed to be as simple as possible: Three fields to configure. Rollback from chat. Migrate to a new machine in one restart.
Let’s get into how and why you might want to use it.
OpenClaw keeps everything local. That’s great until it isn’t.
Your config, sessions, memory databases, hooks, cron jobs—everything that makes your OpenClaw instance yours lives on one machine with no built-in redundancy. Compaction can rewrite session transcripts and cause memory loss. A bad config edit or an accidental deletion means rebuilding from scratch: re-onboarding channels, re-pairing devices, re-teaching your agent who you are.
openclaw-b2-backup adds automatic encrypted backups to Backblaze B2 without changing how you use OpenClaw.
Three fields and you’re done
Setup is intentionally minimal:
openclaw plugins install openclaw-b2-backup
Then open ~/.openclaw/openclaw.json and add your B2 credentials to the entry the installer created:
Restart the gateway, and you’re done. Region is auto-detected from your application key. Encryption is on by default. The first backup runs at midnight, and then daily after that. You can change the schedule to weekly or any cron expression you like.
Free tier friendly: Backblaze B2 includes 10GB of free storage. A typical OpenClaw state directory is 50–500 MB, so even with 10 encrypted snapshots retained, you’ll comfortably stay within the free tier.
Backups that actually happen
The hardest part of any backup system is remembering to run it. This plugin takes care of that with multiple automatic triggers:
A daily cron job (configurable) runs a full incremental push at midnight.
Every time you shut down the gateway, a final push runs before exit—so you always have a snapshot of your latest state.
And, before compaction fires (the thing that rewrites your session transcripts and can cause memory loss), the plugin automatically pushes a snapshot. That last one is the one you’ll be most grateful for.
There’s a 5-minute debounce on the compaction trigger, so rapid-fire compactions don’t queue up a dozen pushes.
Rolling back from chat
The plugin registers a b2_rollback tool with your agent, which means you can manage backups conversationally. Just tell your agent:
“Show me my B2 backup snapshots”
And it’ll list all available snapshots with timestamps. To restore one:
“Roll back to the snapshot from before compaction”Before any restore, the plugin automatically creates a safety snapshot of your current state. Safety snapshots are stored separately and never auto-pruned, so you can always recover from a bad rollback. It’s an undo for your undo.
Moving to a new machine
This was one of the most requested use cases: Getting your entire OpenClaw setup onto a new machine without manually copying files and hoping you got everything.
Install the plugin on your new machine, add the same B2 credentials, and restart. The plugin detects the empty state directory, finds your existing snapshots in B2, and automatically restores the latest one. Same memory, same sessions, same config, same personality. No manual file copying.
openclaw plugins install openclaw-b2-backup
# Add your B2 config to openclaw.json
openclaw gateway restart
# Plugin detects empty state + existing snapshots → auto-restores latest
Security by default
Everything is AES-256-GCM encrypted before it leaves your machine. Each file gets a random salt and IV, so identical files produce different ciphertext. The encryption key is derived from your B2 application key via scrypt—no separate key to manage or lose.
Manifests (which contain only file paths and SHA-256 hashes) stay unencrypted so incremental diffing works regardless of encryption. Credentials and auth profiles are excluded from sync by design—secrets stay per-machine, and you re-auth on new machines.
Best practice: Use a B2 application key scoped to a single bucket for least-privilege access. The plugin works perfectly with bucket-scoped keys—region is auto-detected from the authorize response.
Zero external dependencies
The plugin has no external runtime dependencies beyond croner for scheduling. The B2 client is a hand-rolled AWS Signature V4 implementation using only node:crypto. No AWS SDK, no S3 library, no heavyweight dependencies to audit or keep updated.
It runs entirely inside the gateway process—no external scripts, no separate cron daemon, no stopping the gateway to take backups.
Get started
The plugin is open source (under the MIT license) and available now:
Every neocloud in the market right now is winning or losing on the same battlefield: GPUs. Availability, performance, price per hour. That’s the game, and it’s the right game to play.
But there’s a problem compounding underneath it, one that doesn’t show up in benchmark reports or investor decks, and one that customers will eventually force platforms to confront—neoclouds need highly available, performant storage so that GPUs are never waiting on data.
Neocloud customers need more than compute
Cloud storage isn’t adjacent to what neoclouds sell—for buyers, it’s the difference between a complete platform and a partial one. Neocloud customers need:
Somewhere to put a 10PB training dataset before it touches WEKA, VAST, or DDN boxes
Persistent storage for model checkpoints between training runs
A place for production inference pipelines to pull weights from at scale, fast enough that GPU nodes aren’t sitting idle waiting on data
Most platforms know this. The ones that are honest about it will also tell what happened when they tried to solve it: Engineering sprints planned around storage tooling that competed directly with GPU roadmap work. Ops overhead for infrastructure that customers take for granted when it’s working and blame the platform for when it’s not. Capital allocated to storage hardware and the teams to manage it.
The platforms that figured this out first didn’t hire their way through the problem. They stopped building storage and started shipping it.
Introducing B2 Neo
That’s the insight behind Backblaze B2 Neo. We built it in direct collaboration with the neocloud operators already utilizing Backlaze in production. The result is a white label cloud storage backbone that neoclouds can launch as a native extension of their platform. Here’s what that means in practice:
Up to 1Tbps throughput: Storage that keeps GPU clusters fed and AI workflows moving without becoming the bottleneck.
Launch under your own brand: Branded endpoints, partner-controlled pricing, and a native customer experience that keeps the platform front and center.
API-driven provisioning: Provision accounts, manage permissions, and handle billing through existing platform tools without a separate console or manual setup.
17 years of operational maturity and exabyte scale expertise: Enterprise durability and reliability that customers expect, operated by Backblaze so internal teams don’t have to.
It doesn’t require a storage team. It doesn’t compete with the GPU roadmap. And it doesn’t route customers away from neocloud platforms where their workflows slowly migrate away.
Already in production with leading platforms
Multiple neoclouds are already using B2 Neo. It’s infrastructure that’s already handling AI training workloads, high performance compute (HPC) pipelines, and media delivery at scale and the platforms already running it are direct about why they made the call.
One global edge services platform, after a rigorous technical and business evaluation, put it this way: Their customers were demanding cost-effective yet performant storage as their AI business scaled and Backblaze gave them the ability to deliver cloud object storage as a native extension of their own platform without taking focus away from their roadmap.
Rob Strechay, Principal Analyst at Smuget & theCUBE Research, framed it simply:
With B2 Neo as a first-party service offering to neoclouds, I see the advantage for those organizations of being able to turn on cloud storage without the toil and expense of building it themselves. It is a near-instant value-add offering, helping their customers control costs and achieve the ROI of AI faster.
The question for the rest of the market is how many more quarters of DIY storage ops—or hyperscaler dependency—they can absorb while competitors ship that outcome instead.
B2 Neo is available now. If you’re building a neocloud and storage is either a distraction or a gap, I’d encourage you to talk to us.
The Backblaze Flameflower Startup Program is here, and it’s built by people who’ve been burned before (and that’s a good thing for you).
Startups don’t fail because they pick the wrong cloud storage provider.
They fail because everything else is already hard enough, and infrastructure quietly becomes the thing that slows them down, surprises them, or blows up their budget at exactly the wrong moment.
That’s why we’re launching Flamethrower, the new startup program from Backblaze.
It’s not a gimmick. It’s not a lead trap. And it definitely doesn’t bring the “here’s some credits, good luck” energy.
Flamethrower exists for one simple reason: Founders deserve storage infrastructure that helps them move faster, not learn expensive lessons the hard way.
Why Flamethrower exists
Why Flamethrower?
Startups don’t need more friction, they need a way through it. Metaphor-wise, flames have always been a part of Backblaze’s DNA, and we want this program to speak to the strongest parts of that fire: speed when you need it, reliability when it counts, and power to scale without drama.
Flamethrower takes these ideas and applies it directly to startups, burning away the biggest blockers between you and your next milestone.
I’ve spent most of my career in and around startups, as a founder, an operator, a partner, a mentor, and occasionally as the person explaining to a CFO why last month’s cloud bill looked like a typo.
I’ve seen the pattern repeat over and over:
Early teams optimize for speed (correct)
Infrastructure decisions get made quickly (also correct)
Those decisions quietly become very sticky
And later… someone realizes storage costs are now a board-level discussion
Flamethrower is designed to meet teams before that moment, making your architecture deliberate, not accidental.
Not with abstract promises, but with:
Real infrastructure used in real production environments
Credits that actually help you get to product-market fit
And access to real, live humans who understand what it’s like to build under pressure
Documentation should be written by people who actually use the product
And success shouldn’t be punished with surprise bills
That mindset is exactly why Flamethrower fits here.
This isn’t a side project. It’s an extension of how Backblaze already works with developers and builders, just with a little more gas on the fire (if you will).
I’ve spent years building and running startup programs, developer ecosystems, partnerships, and learning, sometimes painfully, what not to do. I’ve been on the receiving end of “exciting programs” that turned out to be mostly slide decks.
Flamethrower is my attempt (with a very smart team) to build the kind of program I wish existed when I was earlier in my career: practical, honest, and actually useful.
No heroics. No silver bullets. Just support where it counts.
Welcome to our second quarterly Network Stats report covering Q4 of 2025. Along with Drive Stats and Performance Stats, Network Stats pulls back the curtain on real-world infrastructure data, particularly how network-level analytics reflect emerging AI industry trends and usage patterns.
Get more Network Stats (and the details of the dataset)
If you are curious about what metrics we’re recording and how we classify data in this series, check out the details outlined in our Q3 2025 Network Stats report.
One of the roles of the Network Engineering (NetEng) team at Backblaze is to monitor how traffic moves into, out of, and across our platform—not just day-to-day, but over time as customer behavior and industry dynamics evolve. Right now, few forces are reshaping networks faster than AI.
With the launch of B2 Overdrive in April 2025, we built a direct, high-performance path between our storage layers and neoclouds where processing, inference, and modeling take place. It has given us a front-row seat to the impact of AI and how network behavior is changing with it. This quarter, in addition to our regular data analysis, I’ll walk through where AI-driven traffic is concentrated, how ingress and egress patterns showed up, and what the findings say about where AI infrastructure might be headed next.
Continue the conversation
Join us live for the Q4 2025 Network Stats webinar Wednesday, February 4, 2025 at 10:00 a.m. PT / 1:00 p.m. ET. We’ll explore where AI traffic concentrates, how high-magnitude data flows behave, and what early indicators suggest about the future of AI-native infrastructure design.
Can’t make it live, or reading this article after-the-fact? Sign up anyway and catch the recording on demand.
Brave new market
AI workflows don’t just need a place to store data, they need to be able to move it quickly, easily, and nearly constantly for short bursts. Large, multi-petabyte datasets are ingested, transformed, exported for training, pulled back for evaluation, and periodically refreshed as models evolve.
Backblaze plays a key role at both ends of that lifecycle. We serve as a durable storage layer for the initial data ingestion, and as the high-throughput source feeding model training, evaluation, and validation to whatever best neocloud is suitable at the moment. Once that model has been trained, it needs to be stored, served, and periodically retrained, where we serve as the storage medium.
This quarter, we saw a large amount of traffic between Backblaze, neoclouds, and traditional hyperscalers for processing concentrated across the months of June to November. This reflects large-scale ingestion events followed by intensive data manipulation and model-related egress.
From a network perspective, this represents a meaningful shift from diffuse, internet-style traffic patterns to large, high-bandwidth flows between a smaller set of endpoints typical of AI-centric infrastructure.
The neocloud slice
The defining theme of the quarter is “new:” new AI-oriented workflows, new traffic patterns, and leading indicators of new infrastructure trends.
The stacked area graph below shows total traffic by network type over time. While content delivery network (CDN), hosting, and internet service provider (ISP) traffic stayed largely within historical norms reflecting steady-state usage patterns like content delivery, web hosting, and traditional backup workflows, two slices stand out:
Migration traffic: We saw a notable increase in migration traffic from August through October. This classification reflects an influx of data into our network over fiber connections we have in the data centers to cost effectively migrate large amounts of data over private links, not using the public Internet.
Neocloud traffic: We saw a sharp increase in July through November, peaking in October.
Monthly view of all bits transferred to each network type
What do we think is happening? Taken together, these patterns suggest a familiar AI lifecycle: large datasets consisting of assets like images, videos, and metadata are ingested and consolidated then exported for training and experimentation. Now, those assets can be periodically updated as new assets are added and generated models and stored. We see that heading into the new year, the overall baseline has increased indicating a new normal.
Quick terminology refresher
Regions
US-West: Our largest and longest-running region
US-East: Region with the most observed proximity to neocloud infrastructure
CA-East: Our newest region in Canada.
Network Types
CDN: Networks that use Backblaze as an origin store for content delivery
Hosting: Traditional hosting providers that runs workloads like physical or virtual servers for web, database, or application tasks
Hyperscaler: Large, traditional cloud providers
ISP Regional: Local or regional ISPs, think of these as the “last mile” paths as these networks are very close to customer equipment and efficient
ISP Tier1: National or international ISPs that carry our traffic long distances
Neocloud: AI -focused compute networks
Migration: Network links that we use for large-scale data onboarding
Heatmaps: Where AI traffic concentrates
To better understand where AI activity is happening, we thought it would be interesting to isolate the different Backblaze regions and to view concentrations of metrics visualized through heatmaps. We’re going to look at the following three dimensions:
Total traffic volume: Where did we send and receive the most traffic?
Magnitude: Where were the data transfers with the most bits per unique IP address?
Uniqueness: What does the number of distinct IP addresses look like?
Heatmap #1: Where did we send and receive the most traffic?
Unsurprisingly, US-West ISP-Regional traffic dominates in total traffic volume. This region has the largest data center footprint behind it, with connectivity to internet exchanges (IX) such as Equinix-IX that were brought online in 2023. Internet exchanges bring us closer to consumer networks, where we can deliver traffic with lower latency.
More interesting, however, is the US-East neocloud concentration. Our flow data shows neocloud activity clustering in regions including Chicago, Dallas-Houston, Denver, New York, Northern Virginia (Reston/Ashburn corridor), and Atlanta—skewed more towards the East Coast where there’s dense AI compute availability.
From a performance standpoint, this makes sense. It’s important to keep latency (the time between the source and destination) lower to achieve consistent high bandwidth rates for AI data transfers. For now, that gravity is pulling activity towards the East coast.
Total number of bits transferred across our regions to each network type
Will neocloud traffic concentrations shift over time? Since this is our first quarter with a full dataset, it’s a bit early to draw long-term conclusions. But this is exactly the kind of trend we’ll be tracking. Stay tuned for future Network Stats reports.
Heatmap #2: Where were the data transfers with the most magnitude (bits per IP address)?
Another metric we record is bits per IP or what we termed in our last report “magnitude.” This combination of the amount of traffic transferred with how many actors are involved per network is a good proxy to measure how heavy or impactful individual data flows are. In short:
High volume, many IPs: Easier to distribute and load-balance across infrastructure. And many source and destination pairs means that we can traffic engineer at the WAN layer, sending some traffic over one provider and some over another.
High volume, few IPs: More difficult, but more interesting, from a NetEng perspective.
Magnitude transferred across our regions to each network type
With B2 Overdrive, we routinely support client transfers starting at 100Gbps up to 1Tbps of throughput.These high-magnitude flows show up clearly in the data, especially in regions serving AI-heavy neocloud endpoints. Seeing these patterns emerge in the data validates that customers are actively using the platform the way it was designed.
Heatmap #3: How many unique addresses do we interact with?
Uniqueness—measured by the number of distinct IP addresses per network type—adds another dimension to the story.
US-West shows the highest overall uniqueness, driven by its larger number of data centers and mix of workloads.
Neocloud traffic, by contrast, tends to involve fewer, more persistent endpoints, consistent with AI pipelines that rely on stable, long-standing connections between storage and compute.
This contrast reveals a broader trend: AI networking is less about many-to-many communication and more about sustained high-throughput relationships between specialized systems.
Communication uniqueness across our regions to each network type
Summary: Early indicators of an AI-native network era
This quarter represents an early but important snapshot of how AI is reshaping network behavior:
AI-driven traffic is concentrated and heavy (not groundbreaking news by any means, but interesting to see it played out on a network).
Neocloud connectivity is a defining feature of data movement today.
Data gravity is pulling storage, compute, and network design into tighter alignment.
This is our first look at these patterns specifically. As we gather more quarters of data, we’ll be watching closely to see how cyclical neocloud activity becomes, how regional concentrations shift, and how the growing ecosystem of AI-focused ISVs continues to change the shape of the network.
Quarter over quarter data
Last quarter we started capturing data and metrics that we were interested in tracking over time. This represents our first full quarter of data as we only started tracking in August of 2025, so it’s still early to start to see trends, but we’re including the visualizations for fidelity.
First let’s take a look at where all our traffic goes from a global perspective with an updated view of last quarter.
Sankey diagram of all August ingress and egress traffic grouped by type of network
Traffic to other clouds has increased (36.2% to 49.6%) since we last reported in August of 2025, with a slight decrease (19.8% to 18.4%) in Neocloud destinations, but a large increase (3.5% to 18%) to hyperscalers. It’s too early to call these things statistically significant trends or patterns that impact the cloud storage industry broadly, because they’re reflective of what types of customers Backblaze specifically has and our sampling range is only a quarter. That said, we do see an overall increase in cloud to cloud traffic, but the higher percentage to the type of clouds rotated from last quarter.
Next, let’s look at the magnitude of our network traffic based on the category of the traffic destination. As a reminder, magnitude represents the amount of traffic transferred with how many actors are involved per network.
Next, to be consistent with our previous report, we’ll look at magnitude on a linear scale.
With more datapoints, we can clearly see the magnitude of the neocloud and hyperscaler transfers when compared to other network types. As above, it’s a bit early to claim concrete quarter over quarter patterns, but we’ll keep monitoring and updating the dataset.
What’s next?
Next quarter will be the first where we have true quarter over quarter data to analyze, and we’ll be back with more on how AI-driven flows change quarter over quarter. And as we get more data, we’re interested in looking at other trends like IPv4 vs. IPv6 traffic, cross-cloud connectivity trends, and revisiting the concentration analysis we did this quarter.
Anything specific you want to see? Let us know in the comments or reach out to our Evangelism team. Or, keep up-to-date with the latest technical content with our Developer Newsletter.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.


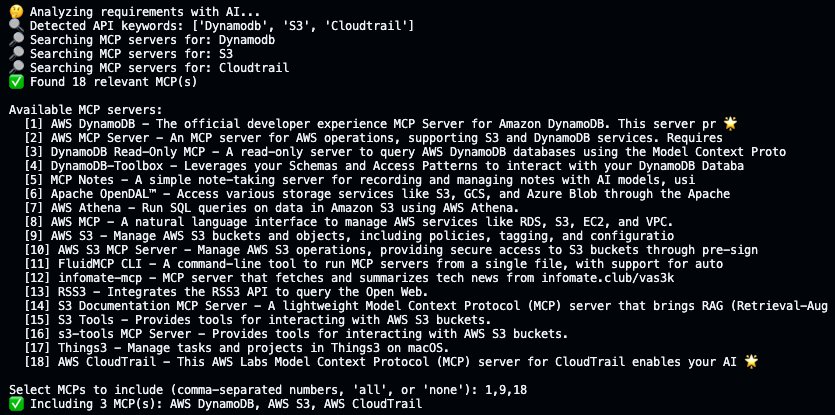
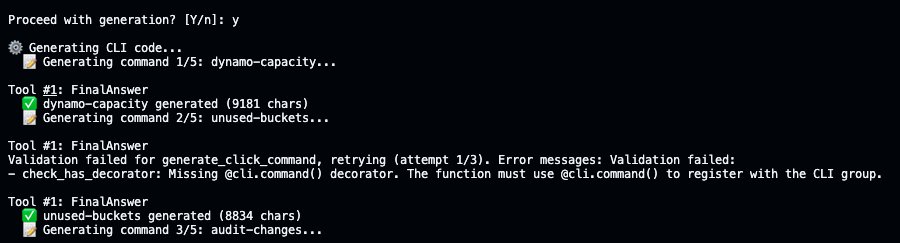
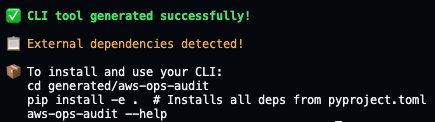
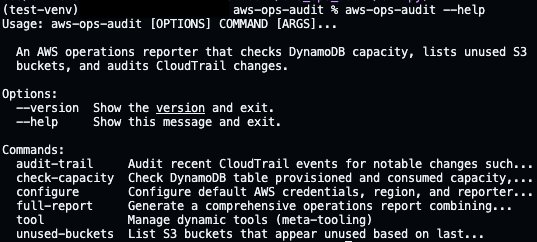


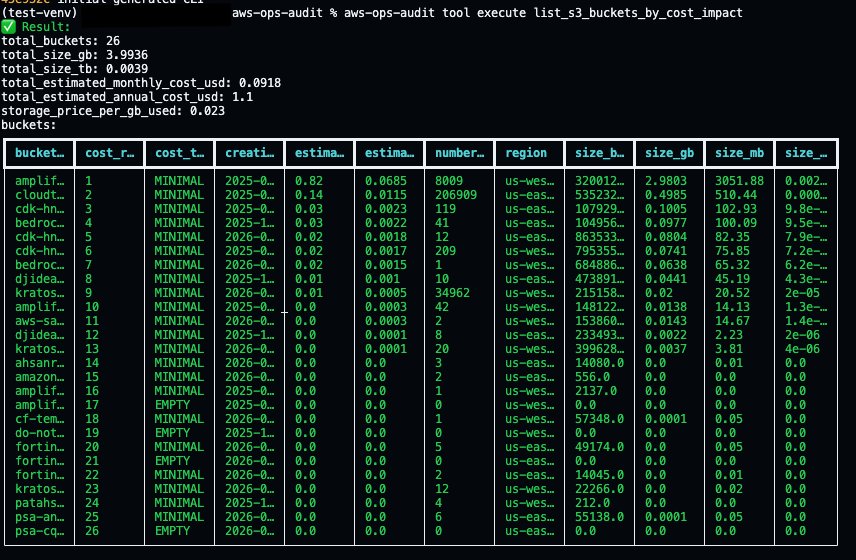
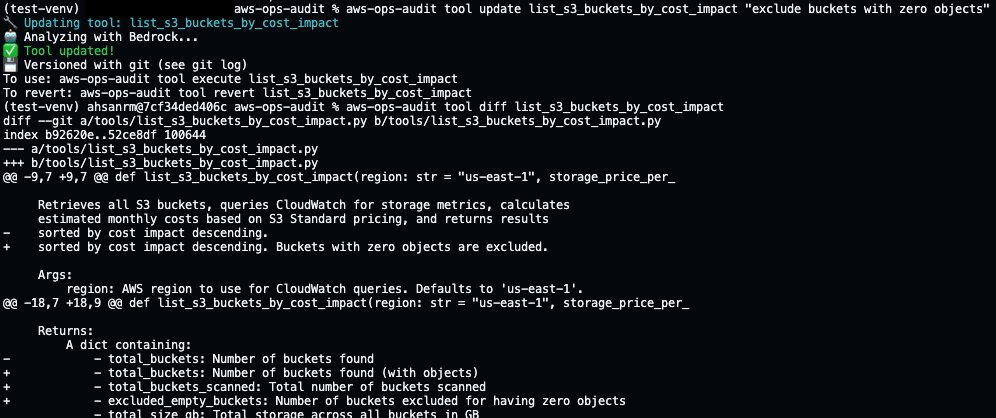
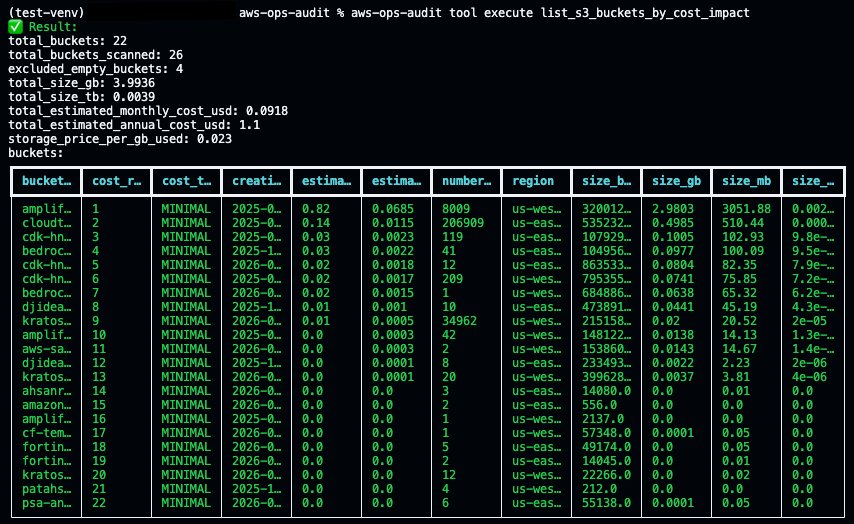


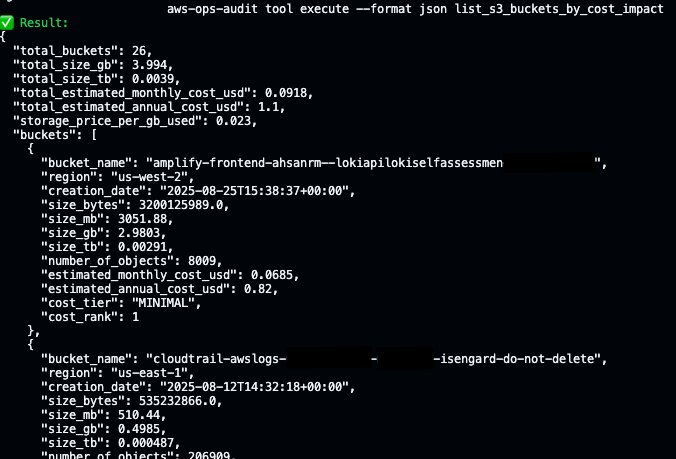
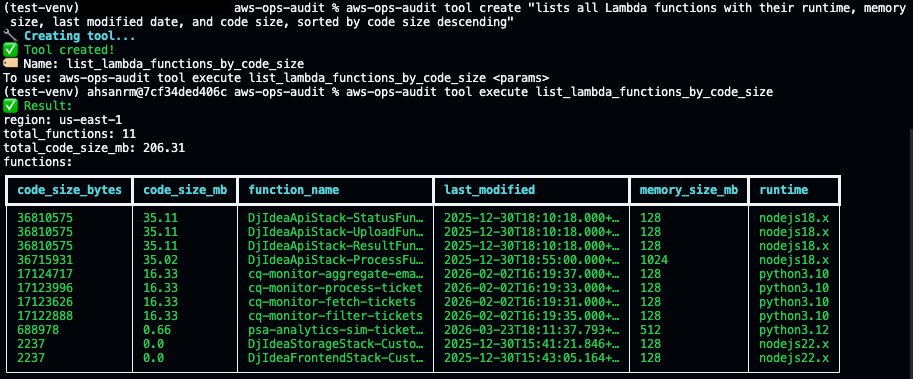

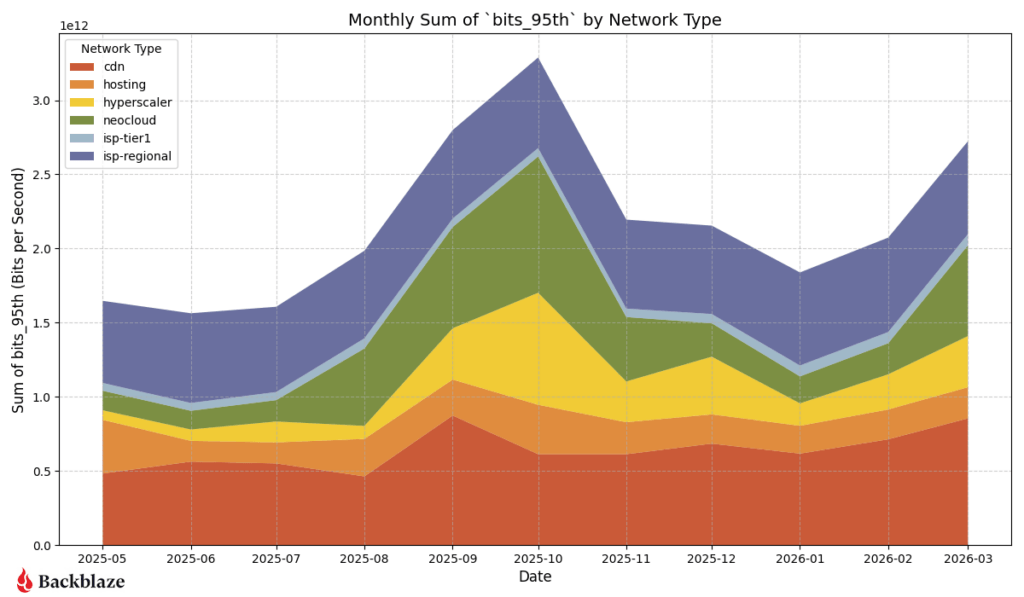
 ISP-Regional traffic continues to be a hotspot on the heatmap, as expected. This region has the largest footprint behind it and connections to internet exchanges (IX). This quarter, with a lull in neocloud and hyperscaler traffic over the winter period, we saw an increase in traffic to our CDN partners. The amount of traffic to CDN networks in the US-West, US-East, and EU-Central regions all increased quarter over quarter.

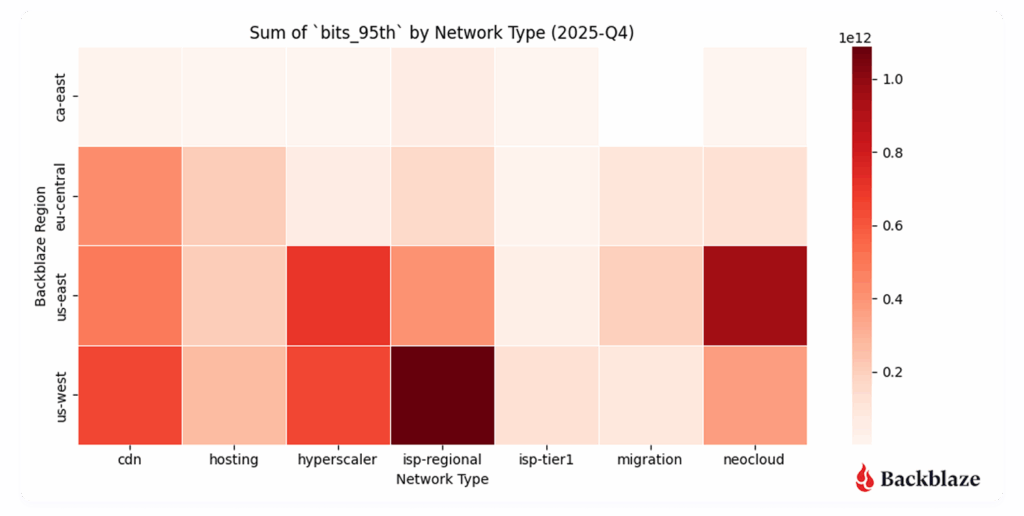
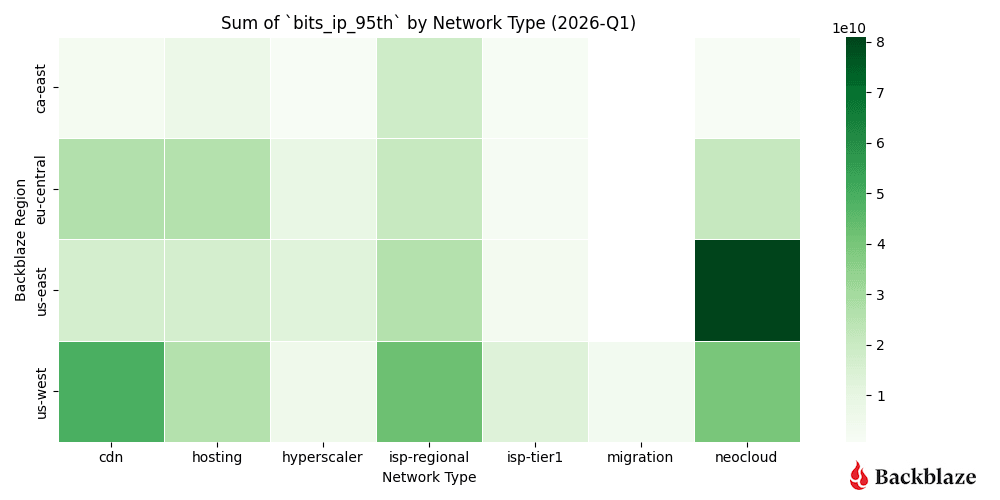
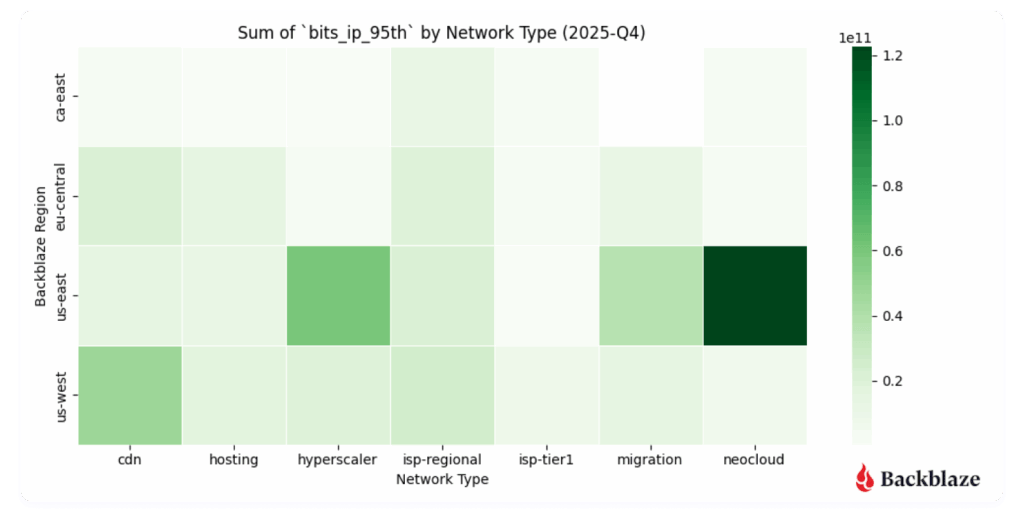

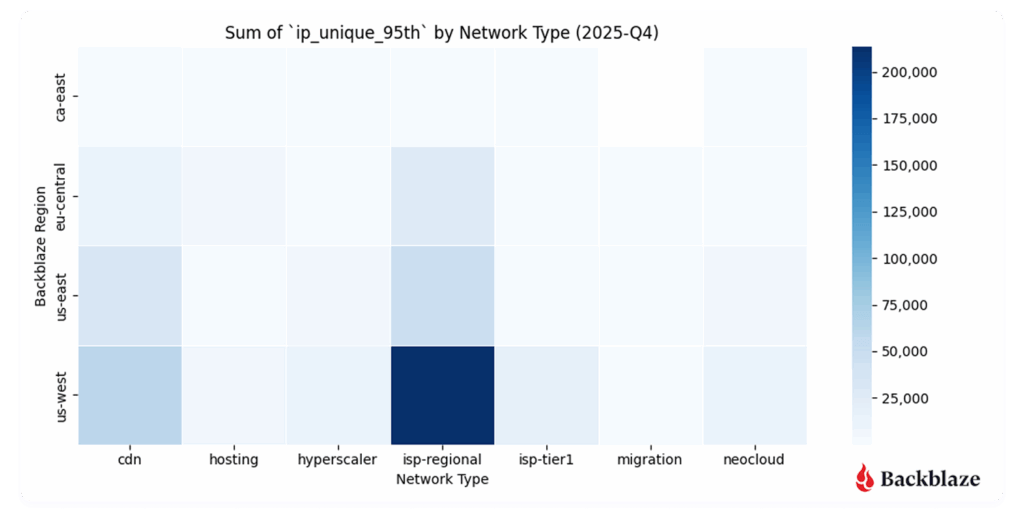
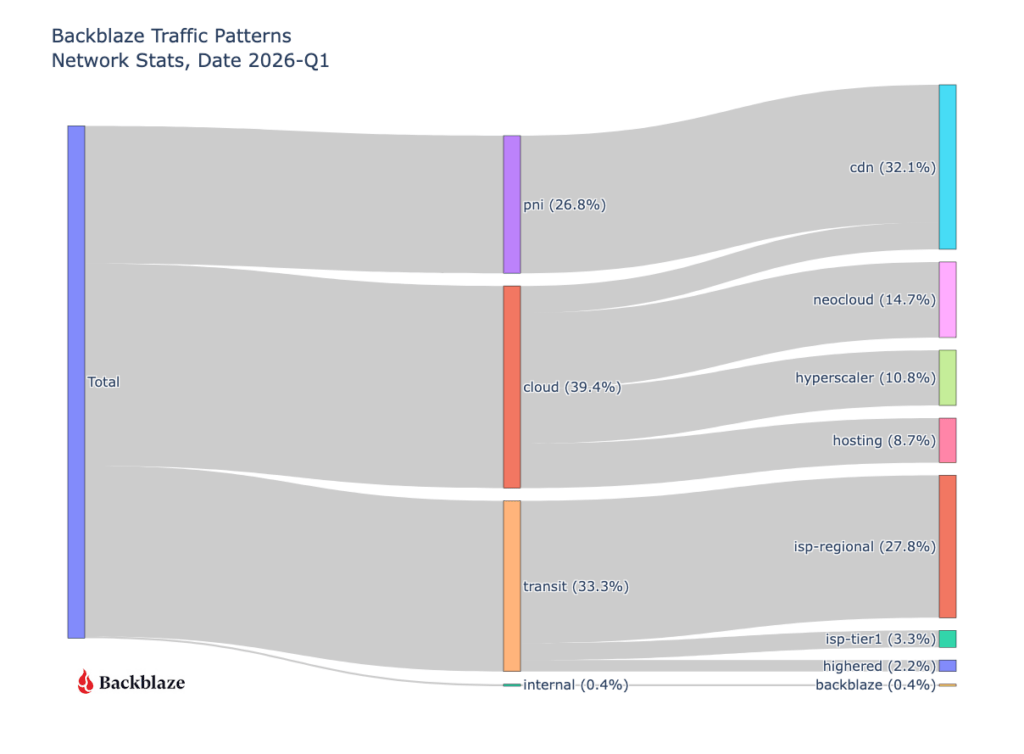

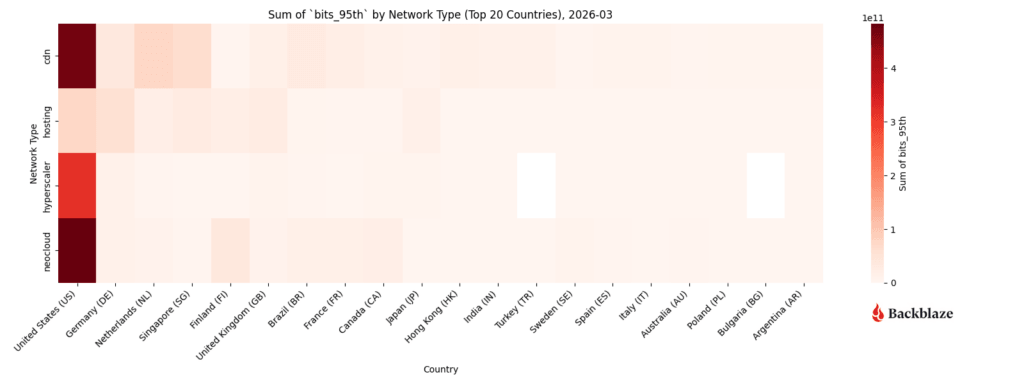
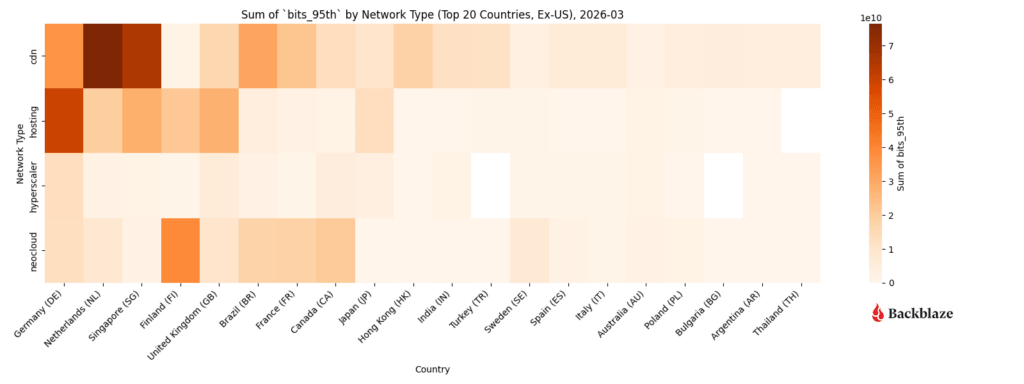
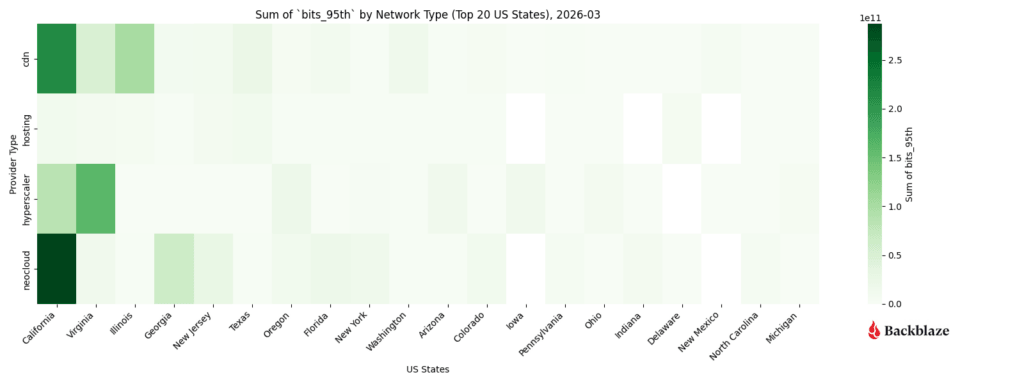

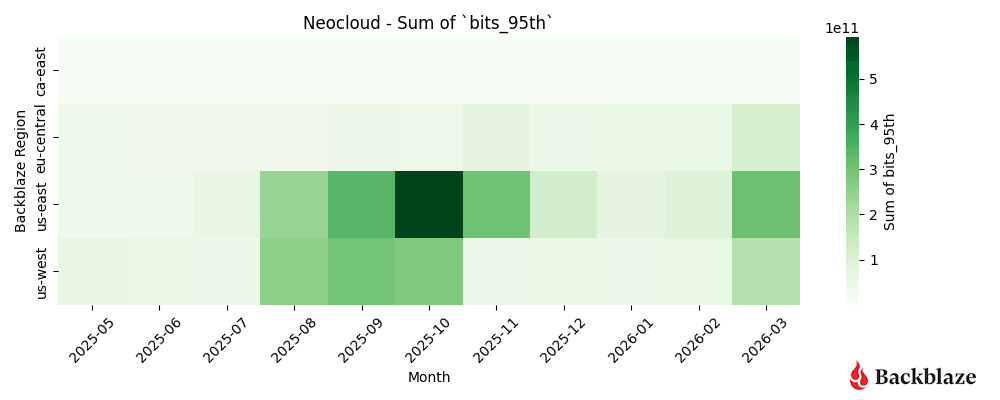
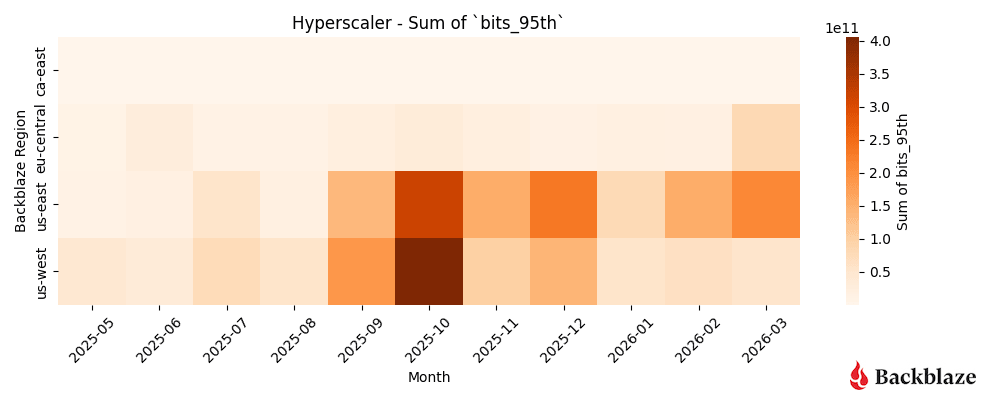

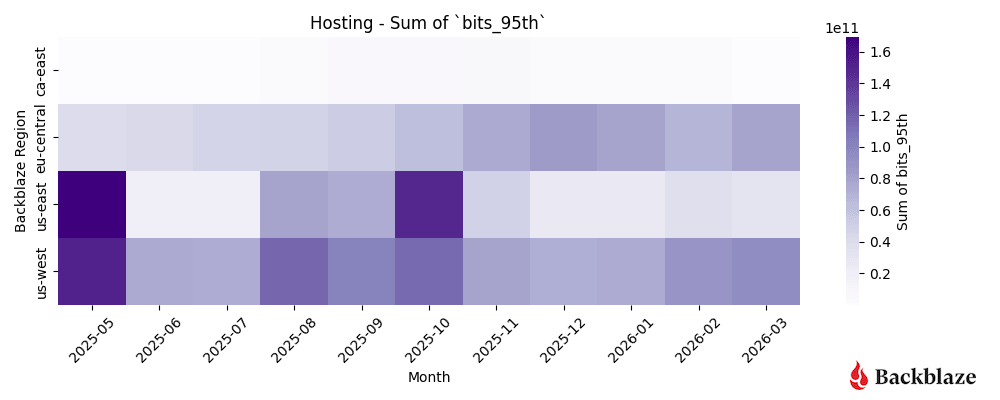
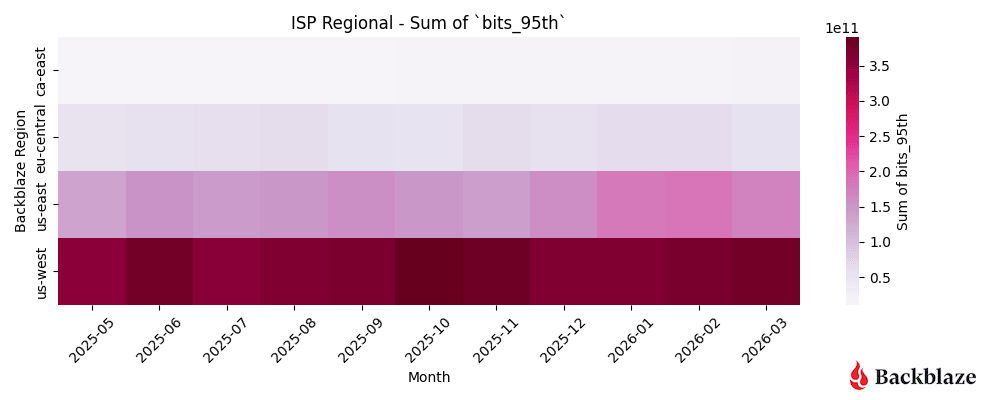
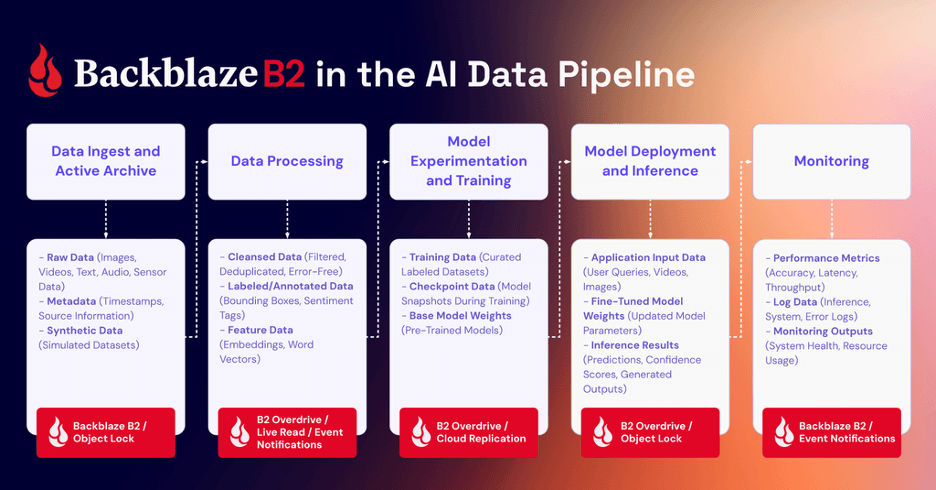
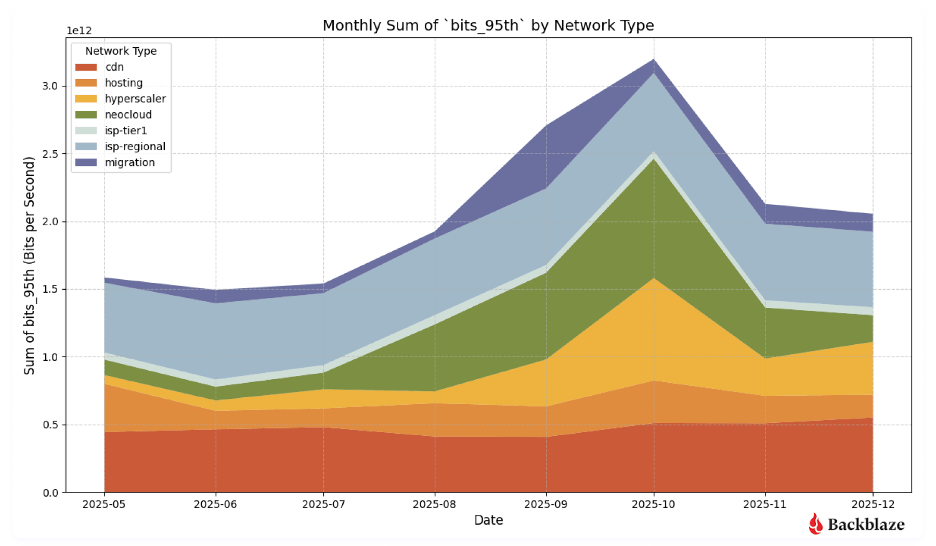
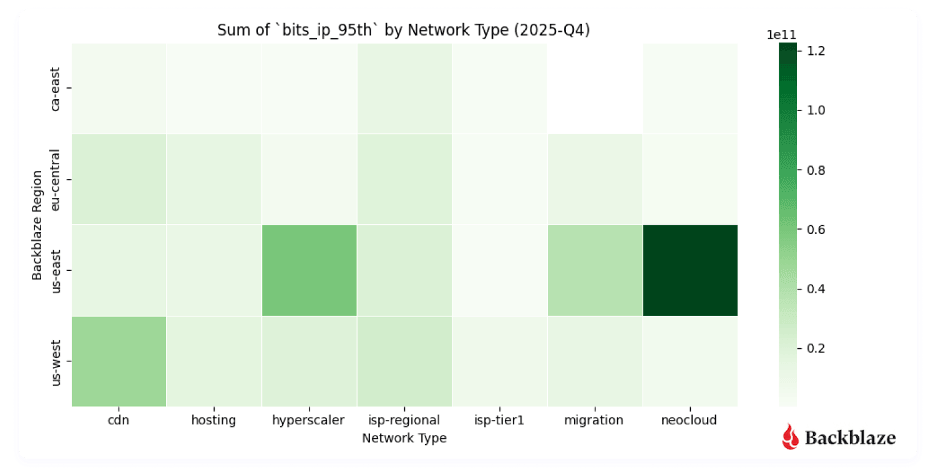
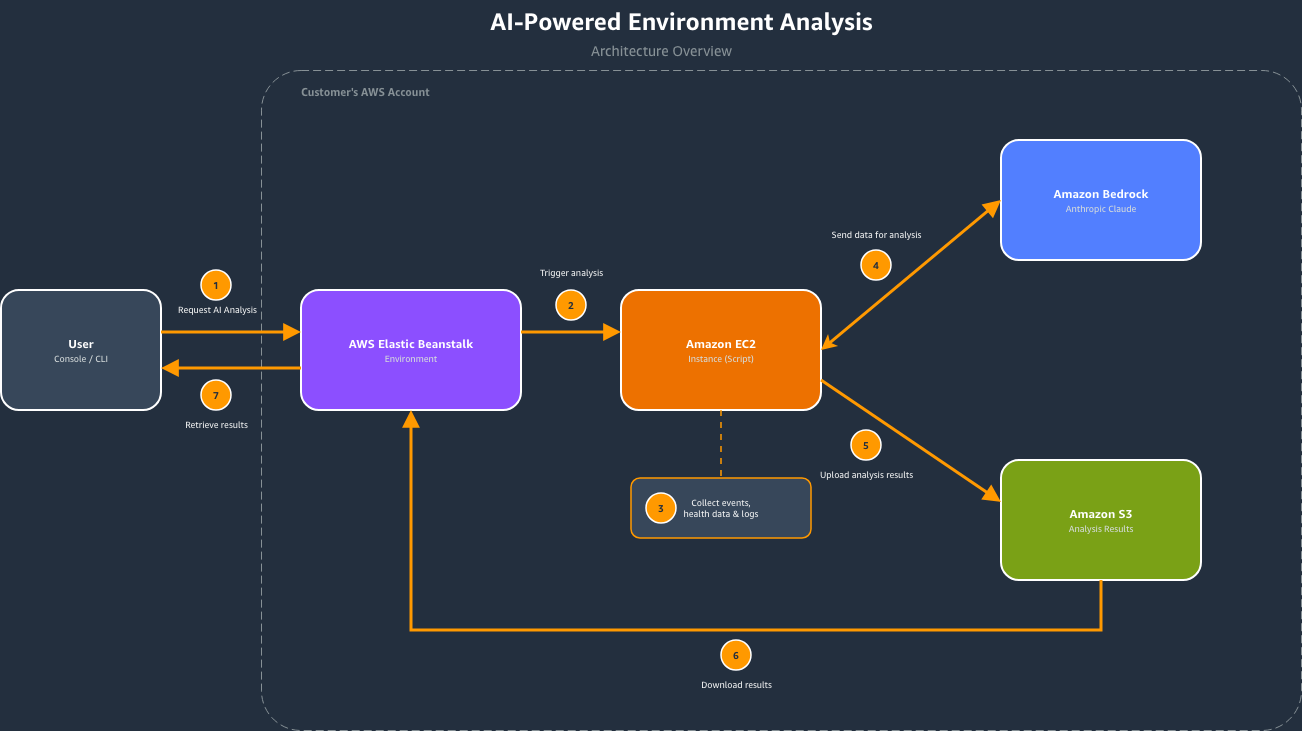
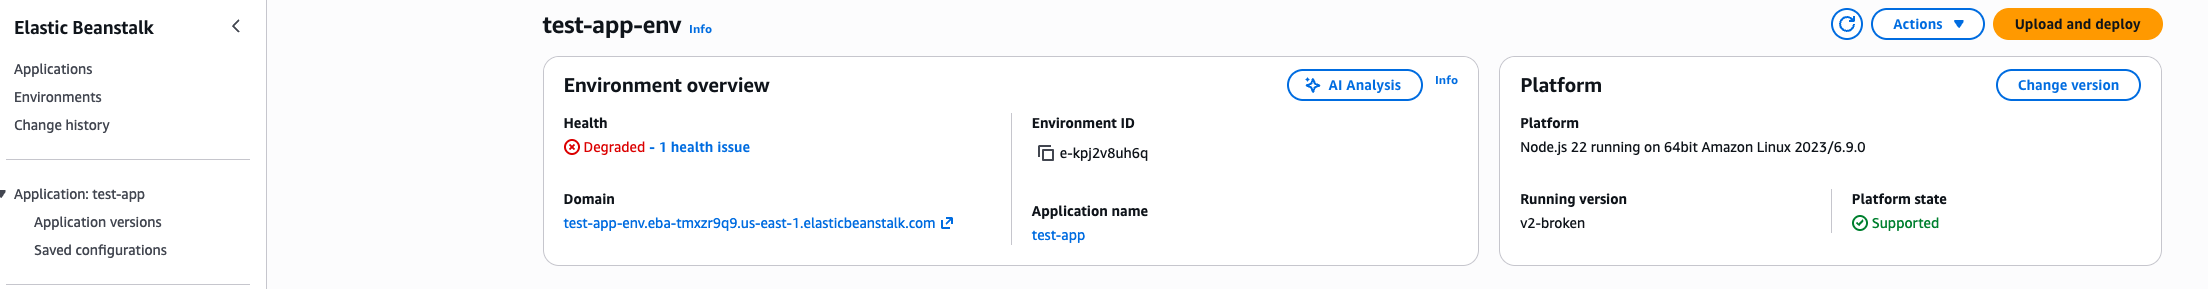
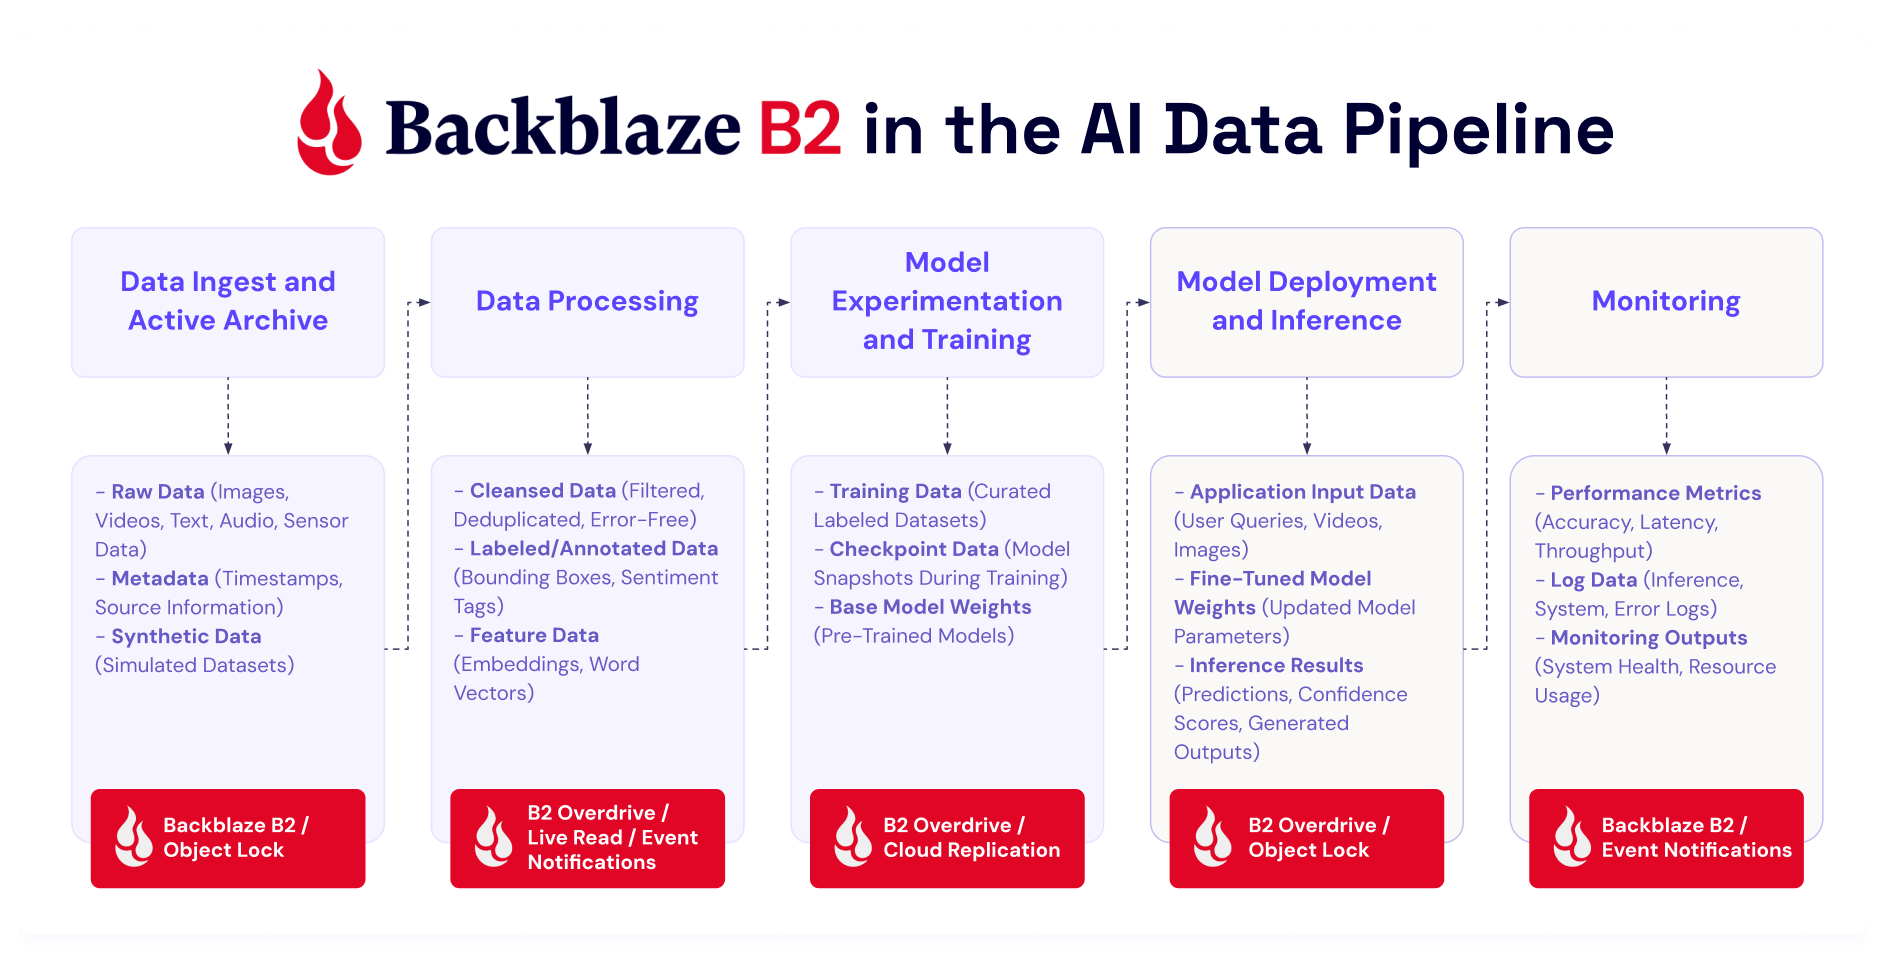

 ISP-Regional traffic dominates in total traffic volume. This region has the largest data center footprint behind it, with connectivity to internet exchanges (IX) such as