Kafka clients that are running outside of AWS (on-premises environment or other clouds) would require an IAM user with a long-lived access key to be provided as part of their codebase or in their server configuration. From a security perspective, there is an additional risk if anyone gains access to those long-term credentials, as they would have access to that AWS account.
In this post, we demonstrate how to use AWS IAM Roles Anywhere to request temporary AWS security credentials, using x.509 certificates for client applications which enables secure interactions with an Amazon Managed Streaming for Apache Kafka (Amazon MSK) cluster. The solution described in this post is compatible with both Amazon MSK Provisioned and Serverless clusters.
Introduction to AWS IAM Roles Anywhere
AWS Identity and Access Management (IAM) Roles Anywhere allows you to obtain temporary security credentials in IAM for workloads running outside of AWS, such as servers, containers, and applications.
By using IAM Roles Anywhere, your workloads can utilize the same IAM policies and roles used by AWS applications to access AWS resources. This eliminates the need to manage long-term credentials for kafka clients running outside AWS. By associating one or more roles with a profile and enabling IAM Roles Anywhere to assume these roles, your applications can employ the client certificate issued by your Certificate Authorities (CAs) to securely initiate requests to AWS. Consequently, your applications obtain temporary credentials, granting them access to the AWS environment.
IAM access control for Amazon MSK allows you to manage both authentication and authorization for your Amazon MSK cluster at no extra cost. This eliminates the necessity of using separate mechanisms for authentication and authorization. We recommend Amazon MSK customers use IAM Access Control unless they have a specific need for using mutual TLS or SASL/SCRAM authN/Z.
In the following sections, we show you how to implement a secure Kafka client machine with a detailed step-by-step tutorial using an AWS IAM Roles Anywhere to connect with a MSK Cluster.
Solution overview
The following diagram illustrates the solution architecture.
The flow of the architecture is as follows:
The session token query from your client machine is directed to an AWS IAM Roles Anywhere endpoint, facilitated by the exchange of X.509 certificates.
IAM Roles Anywhere validates the certificate and retrieves a temporary session token from STS, which is then returned to the client machine.
In Amazon MSK Serverless , the interface endpoint is a collection of one or more elastic network interfaces with a private IP address within your account. It serves as the entry point for traffic directed towards a MSK Serverless service.
Prerequisites
The instructions provided in this post assume that you are already acquainted with the process of creating an MSK serverless cluster and a client machine. Furthermore, it is presumed that you have successfully accomplished the following tasks:
To enable IAM Roles Anywhere for your on-premises Kafka client machine, you must configure two essential components in AWS Roles Anywhere: the trust anchor and the profile. The trust anchor establishes the trust relationship between Roles Anywhere and your certificate authority. This trust is utilized for authenticating certificates to obtain credentials for an IAM role. Profiles are predefined sets of permissions that are applied once successful authentication with Roles Anywhere has been achieved.
Step 1: Generate a CA
An X.509 certificate plays an important role in facilitating communication between the client machine and Roles Anywhere. You can use Public Key Infrastructure (PKI) platform of your choice to establish a certificate authority (CA).
Go to Roles Anywhere console and open the Create a trust anchor page.
Provide a name for your trust anchor and select the private CA that we created in step 1. If you prefer to use your own external CA, choose the External certificate bundle option and provide the necessary certificate bundle.
Choose create a trust anchor button to finish the process.
Step 3: Create and configure a role that trusts IAM Roles Anywhere
Now we create a role that you want your on-premises Kafka client machine to assume after authenticating to IAM Roles Anywhere.
The trust policy of the role should contain the following:
Select the role we created in Step 3 and create the Roles Anywhere profile.
Step 5: Test the client machine
Now that we have successfully set up Roles Anywhere by creating a trust anchor and a profile, the next step is to test the client machine’s communication with Roles Anywhere. This involves retrieving a session token and establishing communication with the MSK broker.
Create a .pem file and copy all the certificate contents into this .pem file(e.g. private_key. pem) and run below command to generate a decrypted version of certificate.
Download the credential helper and use this signing helper tool to test and confirm the functionality from your client machine. We offer the ARNs of the trust anchor and profile of Roles Anywhere, and the role we created in IAM.
You should receive the session credentials successfully from IAM Roles Anywhere.
After verifying the successful setup, proceed to update or create the ~/.aws/config file. Add the signing helper as a credential_process in this file to enable unattended access for the on-premises server. [default]
To stop incurring costs, it is recommended to manually delete the IAM Role, Profile, Trust Anchor, Policies, requested certificate in ACM and created certificates in AWS Private CA.
In this post, we showed you how to utilize AWS IAM Roles Anywhere to generate temporary session tokens for accessing MSK brokers from client machines outside of AWS. By implementing this approach, the security posture of Kafka clients connecting to MSK from outside of AWS are enhanced, allowing customers with stringent security requirements to confidently adopt MSK.
If you have any questions, you can start a new thread on AWS re:Post or reach out to AWS Support.
Organizations running Apache Kafka as their streaming platform need comprehensive monitoring to maintain reliable operations. Without proper visibility into broker health, resource utilization, and data flow metrics, teams risk service disruptions, data loss, and degraded performance that can impact critical business operations. Effective monitoring and alerting are essential to detect anomalies early, from high system load to connectivity issues, enabling teams to take preventive action before problems affect production workloads.
Amazon Managed Streaming for Apache Kafka (Amazon MSK) addresses these monitoring challenges by publishing detailed metrics to Amazon CloudWatch. The service emits metrics at 1-minute intervals for provisioned (Standard) clusters, with flexible monitoring levels (DEFAULT, PER_BROKER, PER_TOPIC_PER_BROKER, or PER_TOPIC_PER_PARTITION) to control granularity and cost. At the DEFAULT level (free), cluster-level metrics are available; higher levels (paid) expose broker-level, per-topic and per-partition metrics.
In this post, I show you how to implement effective monitoring for your MSK clusters using Amazon CloudWatch. You’ll learn how to track critical metrics like broker health, resource utilization, and consumer lag, and set up automated alerts to prevent operational issues. By following these practices, you can work to improve streaming operations reliability, optimize resource usage, and support high availability for your mission-critical applications.
Key metrics to monitor
This article groups important Amazon MSK metrics into logical categories. For each, we highlight key metrics and what they indicate:
Broker Health and Cluster Availability:
ActiveControllerCount is a cluster-level metric where each broker reports whether it’s the active controller (1) or not (0). In a healthy cluster, exactly one broker serves as the active controller at any time. When viewing this metric with the average statistic, the value equals 1 divided by the number of brokers. For example, a 3-broker cluster shows 0.33 (1/3). Set CloudWatch alarm thresholds accordingly—for 6 brokers, alert if average falls below 0.166(1/6). When using the sum statistic, the value should always be 1, indicating one active controller regardless of cluster size. If the sum differs from 1, a controller election is in progress—typically during maintenance activities, configuration changes, or rolling restarts. Note: For a KRaft-based clusters, the ActiveControllerCount is only exposed on dedicated controller endpoints so the sample count is 3 and only controller will report value of 1. Thus, the average is always 0.33 no matter how many brokers there are in the cluster. To monitor the broker health for Kraft-based clusters, check LeaderCount metric. If a broker is not emitting any metric, then it’s a good indication that broker might be unhealthy.
OfflinePartitionsCount (cluster): Number of partitions with no active leader. Non-zero values mean data is temporarily unavailable or unwritable. Trigger alerts if it rises above 0.
UnderReplicatedPartitions (per broker): Number of partitions where not all replicas are caught up. This should stay at 0 under normal conditions. Spikes indicate traffic exceeds capacity or replication lag; sustained values often mean a configuration/ACL issue. Refer to Troubleshoot your Amazon MSK cluster
UnderMinIsrPartitionCount (per broker): Partitions below the minimum in-sync replica (ISR) count. A non-zero value means potential data loss risk if brokers fail. Monitor to ensure replication is healthy. Refer to Custom configurations
GlobalPartitionCount (cluster): Total number of partitions across all topics (leaders only). Useful for capacity planning and sanity checks.
CPU: Total broker CPU utilization is defined as CpuUser + CpuSystem. Best practice is to keep average CPU utilization under 60% . Set alarms on the sum of user+system to detect overload.
CPUCreditBalance / CPUCreditUsage (per broker): For burstable instance types(T3), tracks earned/spent CPU credits. A declining credit balance or high credit usage warns that the instance may be CPU-starved.
Memory: MemoryUsed, MemoryFree (per broker) show RAM usage. Critically, HeapMemoryAfterGC (per broker) reports JVM heap usage (%) after garbage collection. AWS recommends alerting if HeapMemoryAfterGC exceeds 60%, to avoid out-of-memory issues.
Disk: Kafka brokers use attached EBS storage for topic data. Monitor KafkaDataLogsDiskUsed (per broker) – percentage of disk used by message logs. Best practice: alarm when data log usage exceeds 85%. Also track RootDiskUsed: the percentage of the root disk used by the broker.
EBS I/O: Volume metrics (per broker) such as VolumeQueueLength, VolumeReadOps, VolumeWriteOps, VolumeReadBytes, VolumeWriteBytes indicate I/O latency and throughput. Rising queue lengths or latency (such as VolumeTotalReadTime) suggest disk contention.
Network: Basic network stats per broker include NetworkRxPackets, NetworkTxPackets, and errors/drop counts (NetworkRxErrors, NetworkTxErrors, NetworkRxDropped, NetworkTxDropped). Unexpected errors or drops can indicate network issues.
Topic and Partition Activity:
Throughput: BytesInPerSec and BytesOutPerSec measure inbound/outbound data rates per broker or per topic. Sustained drops can signal lost producers/consumers; spikes may require scaling.
Replication Traffic: ReplicationBytesInPerSec/ReplicationBytesOutPerSec (per topic) show inter-broker replication volume.
Consumer Lag: Consumer lag metrics quantify the difference between the latest data written to your topics and the data read by your applications. Amazon MSK provides the following consumer-lag metrics, which you can get through Amazon CloudWatch or through open monitoring with Prometheus: EstimatedMaxTimeLag, EstimatedTimeLag, MaxOffsetLag, OffsetLag, and SumOffsetLag. For information about these metrics, see Amazon MSK metrics for monitoring Standard brokers with CloudWatch.
Client Connections :
ConnectionCount (per broker): Total active connections (clients + inter-broker). Sudden drops or sustained high counts (hitting limits) merit attention.
ClientConnectionCount (per broker, with auth filter): Active authenticated client connections.
ConnectionCreationRate / ConnectionCloseRate (per broker): New or closed connections per second. Spikes in connection churn may indicate client issues.
Authentication: IAMNumberOfConnectionRequests and IAMTooManyConnections (per broker) show IAM auth request rates and throttle breaches (limit of 100 simultaneous connections).
Network Bandwidth Metrics:
TrafficShaping > 0 (any throttling) metric serves as your primary warning signal. When this value exceeds zero, your MSK cluster is experiencing network throttling at the EC2 layer, with packets being dropped or queued due to exceeded allocations. This throttling manifests as reduced throughput, increased latency, and potential network errors that impact both producer and consumer performance. TrafficShaping issues stem from two possible bandwidth limitations: BwInAllowanceExceeded & BwOutAllowanceExceeded :
BwInAllowanceExceeded tracks when inbound aggregate bandwidth surpasses broker maximums.
BwOutAllowanceExceeded monitors when outbound aggregate bandwidth exceeds limits. Both BwInAllowanceExceeded and BwOutAllowanceExceeded metrics directly contribute to overall network throttling events.
Other Operational Metrics:
Thread Pools: RequestHandlerAvgIdlePercent, NetworkProcessorAvgIdlePercent (per broker) show how busy Kafka’s internal thread pools are. Consistently low idle (%) can indicate bottlenecks.
ZooKeeper: For ZooKeeper-based MSK clusters, ZooKeeperRequestLatencyMsMean and ZooKeeperSessionState reflect ZK performance (for older Kafka versions that use Zookeeper). For ZooKeeperSessionState, anything other than 1 for 5-10 mins should be alarming as there can be chances broker has an issue or zookeeper is not able to connect to brokers due to some intermittent network issue.
Tiered Storage: For clusters with tiered storage enabled, Amazon MSK provides metrics like RemoteFetchBytesPerSec, RemoteCopyBytesPerSec, RemoteLogSizeBytes, and related error/queue metrics. These track offloading to remote storage.
Intelligent rebalancing metrics: For MSK Provisioned clusters using Express brokers, Amazon MSK provides two key metrics to monitor rebalancing operations: RebalanceInProgress and UnderProvisioned metrics. See Monitor Intelligent rebalancing metrics
By grouping metrics into these categories, you can build dashboards and alerts that comprehensively cover Amazon MSK health and performance. Amazon CloudWatch also provides automatic dashboards for Amazon MSK.
Let’s take a quick look on how to access CloudWatch automatic dashboard. In the AWS Console, go to the CloudWatch service. When in the CloudWatch console, select Dashboards. Open the Automatic dashboard tab and search for MSK in the Filter Bar.
These dashboards offer per-configured visualizations of key metrics, enabling quick insights into the health and performance of your MSK clusters.
Recommended CloudWatch alarms
Setting alarms on key metrics helps catch issues early. Detecting issues early is crucial in streaming applications where every second counts. A single failing broker can trigger a chain reaction – halting data ingestion, backing up upstream systems, and breaking downstream applications. This can quickly escalate from delayed order processing to lost revenue. Proactive monitoring helps catch and fix problems before they impact your business operations. Based on AWS best practices and experience, consider alarms such as:
Metric (Dimension)
Alarm Condition
Rationale
ActiveControllerCount (cluster)
≠ 1 (count)
Only one active controller should exist. Deviation implies cluster instability.
CPU Utilization (Sum(CPUUser+CPUSystem), per broker)
> 60% (average) for 5+ mins
Helps maintain headroom for broker load and maintenance. High CPU may slow processing as outlined in the MSK best practices documentation
HeapMemoryAfterGC (broker)
> 60% (percentage)
Indicates Kafka heap is filling up. Helps prevent OOM by alerting early.
KafkaDataLogsDiskUsed (broker)
≥ 85% (percent)
Warns that disk is nearly full. Helps prevent data loss by providing time for scaling or cleanup.
OfflinePartitionsCount (cluster)
> 0 (count)
Any offline partition means unavailable data. Immediate investigation needed.
UnderReplicatedPartitions (broker)
> 0 (count)
No replicas lagging under healthy conditions. Spikes or sustained lag can indicate overload or ACL misconfiguration.
UnderMinIsrPartitionCount (broker)
> 0 (count)
There must be topics with partitions that have either less in-sync replicas than the min.insync.replicas setting or with RF=MinISR. To find these topics whose partitions are under replicated, use command: <path-to-your-kafka-installation>/bin/kafka-topics.sh –bootstrap-server <bootstrap-server:port> —command-config client.properties –describe –under-min-isr-partitions
ConnectionCount (broker)
Sudden drop (e.g. < 90% of baseline) or spike above high threshold
Detect client connectivity issues or connection floods. Unexpected drops may mean a broker is unreachable. Refer to Amazon MSK Standard broker quota
CPUCreditBalance (for T3 broker)
< some low threshold (e.g. 10 credits)
For burstable instances, alerts when credits are nearly exhausted, which degrades performance.
VolumeQueueLength (broker)
> 0 (sustained) or rising
Indicates I/O operations are queuing, possible disk bottleneck.
NetworkRxErrors/TxErrors (broker)
> 0 (count)
Any network errors can cause packet loss or disconnections.
IAMTooManyConnections (broker)
> 0 (count)
Exceeding IAM connection limit (100) blocks new connections.
Consumer Lag (MaxOffsetLag or SumOffsetLag) (per consumer-group/topic)
> threshold (depends on SLAs, e.g. growing beyond expected)
Alerts on slow consumers so you can scale consumers or investigate backlogs.
TrafficShaping
> 0 (any throttling)
This is an indication that brokers are exceeding their allocated network bandwidth.
These are illustrative thresholds; adjust them for your workload and SLAs. The remaining metrics listed in the CloudWatch metrics for Standard and Express brokers documentation are susceptible to downstream impact from anomalies in the primary metrics above. It is recommended to enable CloudWatch alarms on a single test cluster first to validate thresholds before extending coverage across your MSK fleet.
Conclusion
In this post, we covered the important CloudWatch metrics and alarms for monitoring Amazon MSK clusters effectively. By implementing these recommended alarms, you can proactively detect and respond to potential issues before they impact your Kafka workloads. To learn more about Amazon MSK monitoring, refer to the Amazon MSK Monitoring Best Practices documentation or explore our Amazon MSK Workshops hands-on experience.
As analytical workloads increasingly demand real-time insights, organizations need business data to enter the data lake immediately after generation. While various methods exist for real-time CDC data ingestion (such as AWS Glue and Amazon EMR Serverless), Amazon MSK Connect with Iceberg Kafka Connect provides a fully managed, streamlined approach that reduces operational complexity and enables continuous data synchronization.
In this post, we demonstrate how to use Iceberg Kafka Connect with Amazon Managed Streaming for Apache Kafka (Amazon MSK) Connect to accelerate real-time data ingestion into data lakes, simplifying the synchronization process from transactional databases to Apache Iceberg tables.
Downstream consumers then process these change records to reconstruct the data state before writing to Iceberg tables.
In this solution, you use the Iceberg Kafka Sink Connector to implement the business on the sink side. The Iceberg Kafka Sink Connector has the following features:
Supports exactly-once delivery
Support multi-table synchronization
Support schema changes
Field name mapping through Iceberg’s column mapping feature
Prerequisites
Before beginning the deployment, ensure you have the following components in place:
Amazon RDS for MySQL: This solution assumes you already have an Amazon RDS for MySQL database instance running with the data you want to synchronize to your Iceberg data lake. Ensure that binary logging is enabled on your RDS instance to support Change Data Capture (CDC) operations.
Amazon MSK Cluster: You need an Amazon MSK cluster provisioned in your target AWS Region. This cluster will serve as the streaming platform between your MySQL database and the Iceberg data lake. Ensure the cluster is properly configured with appropriate security groups and network access.
Amazon S3 Bucket: Ensure you have an Amazon S3 bucket ready to host the custom Kafka Connect plugins. This bucket serves as the storage location from which AWS MSK Connect retrieves and installs your plugins. The bucket must exist in your target AWS Region, and you must have appropriate permissions to upload objects to it.
Custom Kafka Connect Plugins: To enable real-time data synchronization with MSK Connect, you need to create two custom plugins. The first plugin uses the Debezium MySQL Connector to read transactional logs and produce Change Data Capture (CDC) events. The second plugin uses Iceberg Kafka Connect to synchronize data from Amazon MSK to Apache Iceberg tables.
Build Environment: To build the Iceberg Kafka Connect plugin, you need a build environment with Java and Gradle installed. You can either launch an Amazon EC2 instance (recommended: Amazon Linux 2023 or Ubuntu) or use your local machine if it meets the requirements. Ensure you have sufficient disk space (at least 20GB) and network connectivity to clone the repository and download dependencies.
Build Iceberg Kafka Connect from open source
The connector ZIP archive is created as part of the Iceberg build. You can run the build using the following code:
git clone https://github.com/apache/iceberg.git
cd iceberg/
./gradlew -x test -x integrationTest clean build
The ZIP archive will be saved in ./kafka-connect/kafka-connect-runtime/build/distributions.
Create custom plugins
The next step is to create custom plugins to read and synchronize the data.
Upload the custom plugin ZIP file you compiled in the previous step to your designated Amazon S3 bucket.
Go to the AWS Management Console and navigate to Amazon MSK and choose Connect in the navigation pane.
Choose Custom plugins, then select the plugin file you uploaded to S3 by browsing or entering its S3 URI.
Specify a unique, descriptive name for your custom plugin (such as my-connector-v1).
Choose Create custom plugin.
Configure MSK Connect
With the plugins installed, you’re ready to configure MSK Connect.
Configure data source access
Start by configuring data source access.
To create a worker configuration, choose Worker configurations in the MSK Connect console.
Choose Create worker configuration and copy and paste the following configuration.
key.converter.schemas.enable=false
value.converter.schemas.enable=false
key.converter=org.apache.kafka.connect.json.JsonConverter
value.converter=org.apache.kafka.connect.json.JsonConverter
# Enable topic creation by the worker
topic.creation.enable=true
# Default topic creation settings for debezium connector
topic.creation.default.replication.factor=3
topic.creation.default.partitions=1
topic.creation.default.cleanup.policy=delete
In the Amazon MSK console, choose Connectors under Amazon MSK Connect and choose Create connector.
In the setup wizard, select the Debezium MySQL Connector plugin created in the previous step, enter the connector name and select the MSK cluster of the synchronization target. Copy and paste the following content in the configuration:
Note that in the configuration, Route is used to write multiple records to the same topic. In the parameter transforms.Reroute.topic.regex, the regular expression is configured to filter the table names that need to be written to the same topic. In the following example, the data containing <tablename-prefix> in the table name is written to the same topic.
For example, after transforms.Reroute.topic.replacement is specified as $1all_records, the topic name created in the MSK is < database.server.name>.all_records.
After you choose Create, MSK Connect creates a synchronization task for you.
Data synchronization (single table mode)
Now, you can create a real-time synchronization task for the Iceberg table. Start by creating a real-time synchronization job for a single table.
In the Amazon MSK console, choose Connectors under MSK Connect
Choose Create connector.
On the next page, select the previously created Iceberg Kafka Connect plugin
Enter the connector name and select the MSK cluster of the synchronization target.
For Iceberg Connector, it will create a topic named control-iceberg by default to record offset. Select the previously created worker configuration that includes topic.creation.enable = true. If you use the default worker configuration and auto-topic creation isn’t enabled at the MSK broker level, the connector will not be able to automatically create topics.
You can also specify this topic name by setting the parameter iceberg.control.topic = <offset-topic>. If you want to use a custom topic, you can use the following code.
Query the synchronized data results through Amazon Athena. From the table synchronized to Athena, you can see that, in addition to the source table field, an additional _cdc field has been added to store the metadata content of the CDC.
Compaction
Compaction is an essential maintenance operation for Iceberg tables. Although frequent ingestion of small files can negatively impact query performance, regular compaction mitigates this issue by consolidating small files, minimizing metadata overhead, and substantially improving query efficiency. To maintain optimal table performance, you should implement dedicated compaction workflows. AWS Glue offers an excellent solution for this purpose, providing automated compaction capabilities that intelligently merge small files and restructure table layouts for enhanced query performance.
Schema Evolution Demonstration
To demonstrate the schema evolution capabilities of this solution, we conducted a test to show how field changes at the source database are automatically synchronized to the Iceberg tables through MSK Connect and Iceberg Kafka Connect.
Initial Setup:
First, we created an RDS MySQL database with a customer information table (tb_customer_info) containing the following schema:
+----------------+--------------+------+-----+-------------------+-----------------------------------------------+
| Field          | Type         | Null | Key | Default           | Extra                                         |
+----------------+--------------+------+-----+-------------------+-----------------------------------------------+
| id             | int unsigned | NO   | PRI | NULL              | auto_increment                                |
| user_name      | varchar(64)  | YES  |     | NULL              |                                               |
| country        | varchar(64)  | YES  |     | NULL              |                                               |
| province       | mediumtext   | NO   |     | NULL              |                                               |
| city           | int          | NO   |     | NULL              |                                               |
| street_address | varchar(20)  | NO   |     | NULL              |                                               |
| street_name    | varchar(20)  | NO   |     | NULL              |                                               |
| created_at     | timestamp    | NO   |     | CURRENT_TIMESTAMP | DEFAULT_GENERATED                             |
| updated_at     | timestamp    | YES  |     | CURRENT_TIMESTAMP | DEFAULT_GENERATED on update CURRENT_TIMESTAMP |
+----------------+--------------+------+-----+-------------------+-----------------------------------------------+
We then configured MSK Connect using the Debezium MySQL Connector to capture changes from this table and stream them to Amazon MSK in real time. Following that, we set up Iceberg Kafka Connect to consume the data from MSK and write it to Iceberg tables.
Schema Modification Test:
To test the schema evolution capability, we added a new field named phone to the source table:
ALTER TABLE tb_customer_info ADD COLUMN phone VARCHAR(20) NULL;
We then inserted a new record with the phone field populated:
INSERT INTO tb_customer_info (user_name,country,province,city,street_address,street_name,phone) values ('user_demo','China','Guangdong',755,'Street1 No.369','Street1','13099990001');
Results:
When we queried the Iceberg table in Amazon Athena, we observed that the phone field had been automatically added as the last column, and the new record was successfully synchronized with all field values intact. This demonstrates that Iceberg Kafka Connect’s self-adaptive schema capability seamlessly handles DDL changes at the source, eliminating the need for manual schema updates in the data lake.
Data synchronization (multi-table mode)
It’s common that data admins want to use a single connector for moving data in multiple tables. For example, you can use the CDC collection tool to write data from multiple tables to a topic and then write data from one topic to multiple Iceberg tables through the consumer side. In Configure data source access, you configured a MySQL synchronization Connector to synchronize tables with specified rules to a topic using Route. Now let’s review how to distribute data from this topic to multiple Iceberg tables.
When using Iceberg Kafka Connect to synchronize multiple tables to Iceberg tables using AWS Glue Data Catalog, you must pre-create a database in the Data Catalog before starting the synchronization process. The database name in AWS Glue must exactly match the source database name, because the Iceberg Kafka Connect connector automatically uses the source database name as the target database name during multi-table synchronization. This naming consistency is required because the connector doesn’t provide an option to map source database names to different target database names in multi-table scenarios.
In this configuration, two parameters have been added:
iceberg.tables.route-field: Specifies the routing field that distinguishes between different tables, specified as cdc.source for CDC data parsed by Debezium
iceberg.tables.dynamic-enabled: If the iceberg.tables parameter isn’t set, it must be specified as true here
After completion, MSK Connect will creates a sink connector for you.
After the process is complete, you can view the newly created table through Athena.
Other tips
In this section, we share some more things that you can use to customize your deployment to fit your use case.
Specified table synchronizationIn the Data synchronization (multi-table mode) section, you specify iceberg.tables.route-field = _cdc.Source and iceberg.tables.dynamic-enabled=true, these two parameter settings can write multiple tables stored in the Iceberg table. If you want to synchronize only the specified tables, you can specify the table name you want to synchronize by setting iceberg.tables.dynamic-enabled = false and then setting the iceberg.tables parameter. For example,
Performance Testing Results We conducted a performance test using sysbench to evaluate the data synchronization capabilities of this solution. The test simulated a high-volume write scenario to demonstrate the system’s throughput and scalability.Test Configuration:
Database setup: Created 25 tables in the MySQL database using sysbench
Data loading: Wrote 20 million records to each table (500 million total records)
Real-time streaming: Configured MSK Connect to stream data from MySQL to Amazon MSK in real time during the write process
Kafka Connect configuration:
Started Kafka Iceberg Connect
Minimum workers: 1
Maximum workers: 8
Allocated two MCUs per worker
Performance Results:
In our test using the configuration above, each MCU achieved peak writing performance of approximately 10,000 records per second, as shown in the following figure. This demonstrates the solution’s ability to handle high-throughput data synchronization workloads effectively.
Clean up
To clean up your resources, complete the following steps:
Delete MSK Connect connectors: Remove both the Debezium MySQL Connector and Iceberg Kafka Connect connector created for this solution.
Delete the Amazon MSK cluster: If you created a new MSK cluster specifically for this demonstration, delete it to stop incurring charges.
Delete the S3 buckets: Remove the S3 buckets used to store the custom Kafka Connect plugins and Iceberg table data. Ensure you have backed up any data you need before deletion.
Delete the EC2 instance: If you launched an EC2 instance to build the Iceberg Kafka Connect plugin, terminate it.
Delete the RDS MySQL instance (optional): If you created a new RDS instance specifically for this demonstration, delete it. If you’re using an existing production database, skip this step.
Remove IAM roles and policies (if created): Delete any IAM roles and policies that were created specifically for this solution to maintain security best practices.
Conclusion
In this post, we presented a solution to achieve real-time, efficient data synchronization from transactional databases to data lakes using Amazon MSK Connect and Iceberg Kafka Connect. This solution provides a low-cost and efficient data synchronization paradigm for enterprise-level big data analysis. Whether you’re working with ecommerce transactions, financial transactions, or IoT device logs, this solution can help you achieve quick access to a data lake, enabling analytical businesses to quickly obtain the latest business data. We encourage you to try this solution in your own environment and share your experiences in the comments section. For more information, visit Amazon MSK Connect.
Modern streaming workloads are highly dynamic—traffic volumes fluctuate based on time of day, business cycles, or event-driven bursts. Customers need to dynamically scale Apache Kafka clusters up and down to maintain consistent throughput and performance without incurring unnecessary cost. For example, ecommerce platforms see sharp traffic increases during seasonal sales, and financial systems experience load spikes during market hours. Scaling clusters helps teams align cluster capacity with increased ingress throughput in response to these variations, leading to more efficient utilization and a better cost-to-performance ratio.
Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express brokers are a key component to dynamically scaling clusters to meet demand. Express based clusters deliver 3 times higher throughput, 20 times faster scaling capabilities, and 90% faster broker recovery compared to Amazon MSK Provisioned clusters. In addition, Express brokers support intelligent rebalancing for 180 times faster operation performance, so partitions are automatically and consistently well distributed across brokers. This feature is enabled by default for all new Express based clusters and comes at no additional cost to customers. This capability alleviates the need for manual partition management when modifying cluster capacity. Intelligent rebalancing automatically tracks cluster health and triggers partition redistribution when resource imbalances are detected, maintaining performance across brokers.
This post demonstrates how to use the intelligent rebalancing feature and build a custom solution that scales Express based clusters horizontally (adding and removing brokers) dynamically based on Amazon CloudWatch metrics and predefined schedules. The solution provides capacity management while maintaining cluster performance and minimizing overhead.
Overview of Kafka scaling
Scaling Kafka clusters involves adding or removing brokers to the cluster while providing balanced data distribution and uninterrupted service. When new brokers are added, partition reassignment is required to evenly distribute load across the cluster. This process is typically performed manually—either through the Kafka command line tools (kafka-reassign-partitions.sh) or by using automation frameworks such as Cruise Control, which intelligently calculates and executes reassignment plans. During scale-in operations, partitions hosted on the brokers marked for removal must first be migrated to other brokers, leaving the target brokers empty before decommissioning.
Challenges of scaling Kafka dynamically
The complexity of scaling depends heavily on the underlying storage model. In deployments where broker data resides entirely on local storage, scaling involves physical data movement between brokers, which can take considerable time depending on partition size and replication factor. In contrast, environments that use tiered storage shift most of the data to remote object storage such as Amazon Simple Storage Service (Amazon S3), making scaling a largely metadata-driven operation. This significantly reduces data transfer overhead and accelerates both broker addition and removal, enabling more elastic and operationally efficient Kafka clusters.
However, scaling Kafka remains a non-trivial operation due to the interplay between storage, data movement, and broker resource utilization. When partitions are reassigned across brokers, large volumes of data must be copied over the network, often leading to network bandwidth saturation, storage bandwidth exhaustion, and elevated CPU utilization. Depending on data volume and replication factor, partition rebalancing can take several hours, during which time cluster performance and throughput might temporarily degrade and often require additional configuration to throttle the data movement. Although tools like Cruise Control automate this process, they introduce another layer of complexity: selecting the right combination of rebalancing goals (such as disk capacity, network load, or replica distribution) requires a deep understanding of Kafka internals and trade-offs between speed, balance, and stability. As a result, efficient scaling is an optimization problem, demanding careful orchestration of storage, compute, and network resources.
How Express brokers simplify scaling
Express brokers manage Kafka scaling through their decoupled compute and storage architecture. This innovative design enables unlimited storage without pre-provisioning, significantly simplifying cluster sizing and management. The separation of compute and storage resources allows Express brokers to scale faster than standard MSK brokers, enabling rapid cluster expansion within minutes. With Express brokers, administrators can adjust capacity both vertically and horizontally as needed, alleviating the need for over-provisioning. The architecture provides sustained broker throughput during scaling operations, with Express brokers capable of handling 500 MBps ingress and 1000 MBps egress on m7g.16xl instances. For more information about how the scaling process works in Express based clusters, see Express brokers for Amazon MSK: Turbo-charged Kafka scaling with up to 20 times faster performance.
Added to this faster scaling capability, when you add or remove brokers from your Express based clusters, intelligent rebalancing automatically redistributes partitions to balance resource utilization across the brokers. This makes sure the cluster continues to operate at peak performance, making scaling in and out possible with a single update operation. Intelligent rebalancing is enabled by default on new Express broker clusters and continuously monitors cluster health for resource imbalances or hotspots. For example, if certain brokers become overloaded due to uneven distribution of partitions or skewed traffic patterns, intelligent rebalancing will automatically move partitions to less utilized brokers to restore balance.
Finally, Express based clusters automate client configuration of broker bootstrap connection strings to allow clients to connect to clusters seamlessly as brokers are added and removed. Express based clusters provide three connection strings, one per Availability Zone, which are independent of the brokers in the cluster. This means clients only need to configure these connection strings to maintain consistent connections as brokers are added or removed. These key capabilities of Express based clusters—rapid scaling, intelligent rebalancing, and dynamic broker bootstrapping—are critical to enabling dynamic scaling in Kafka clusters. In the following section, we explore how we use these capabilities to automate the scaling process of Express based clusters.
On-demand and scheduled scaling
Leveraging fast scaling capabilities of Express brokers together with intelligent rebalancing, you can build a flexible and dynamic scaling solution to optimize your Kafka cluster resources. There are two primary approaches for automatic scaling that balance performance needs with cost efficiency: on-demand and scheduled scaling.
On-demand scaling
On-demand scaling tracks cluster performance and responds to capacity demands. This approach addresses scenarios where workload patterns experience traffic spikes. On-demand scaling tracks Amazon MSK performance indicators as CPU utilization and network ingress and egress throughput per broker. Beyond these infrastructure metrics, the solution also supports using CloudWatch metrics to enable business-logic-driven scaling decisions.
The solution evaluates the performance metrics continuously against configurable thresholds to determine when scaling actions are necessary. When brokers operate above capacity thresholds consistently over a period of time, it invokes an Amazon MSK API to increase the broker count of the cluster. The solution in this post currently supports horizontal scaling (adding and removing brokers) only. Intelligent rebalancing will then automatically redistribute the partitions to spread the load across the new brokers that are added. Similarly, when utilization drops below thresholds, the solution invokes an Amazon MSK API to remove brokers. The rebalancing process automatically moves partitions from the broker marked for removal to other brokers in the cluster. This solution requires topics to have sufficient partitions to support rebalancing to new brokers as brokers are added.
The following diagram illustrates the on-demand scaling workflow.
Scheduled scaling
Scheduled scaling adjusts cluster capacity using time-based triggers. This approach is useful for applications with traffic patterns that correlate with business hours or schedules. For example, ecommerce platforms benefit from scheduled scaling during peak sale periods when customer activity peaks. Scheduled scaling is also useful for customers who want to avoid cluster modification operations during business hours. This solution uses a configurable schedule to scale out the cluster capacity before business hours to handle the anticipated traffic and scale in after business hours to reduce costs. This particular solution currently supports horizontal scaling (adding/removing brokers) only. With scheduled scaling, you can handle specific scenarios such as weekday business hours, weekend maintenance windows, or specific dates. You can also specify the desired number of brokers at scale-out and scale-in.
The following diagram illustrates the scheduled scaling workflow.
Solution overview
This solution provides scaling automation for Express brokers through two approaches:
On-demand scaling – Tracks built-in cluster performance metrics or custom CloudWatch metrics and adjusts broker capacity when thresholds are crossed
Scheduled scaling – Scales clusters based on specific schedules
In the following sections, we provide the implementation details for both scaling methods.
Prerequisites
Complete the following steps as prerequisites:
Create an Express cluster with intelligent rebalancing enabled. The intelligent rebalancing feature is required for this solution to work. Note the Amazon Resource Name (ARN) of the cluster.
The solution uses an AWS Lambda function that is triggered by an Amazon EventBridge scheduler periodically. The Lambda function checks the cluster state and time since the last broker addition or removal was done. This is done to determine if the cluster is ready to scale. If the cluster is ready for scaling, the function collects the CloudWatch metrics that need to be evaluated to make the scaling decision. Based on the scaling configuration and using the metrics in CloudWatch, the function evaluates the scaling logic and executes the scaling decision. The scaling decision can lead to addition or removal of brokers to the cluster. In both cases, intelligent rebalancing handles partition distribution across brokers without manual intervention. You can find more details of the scaling logic in the GitHub repo.
The following diagram illustrates the architecture of the on-demand scaling solution.
Deploy on-demand scaling solution
Follow these steps to deploy the on-demand scaling infrastructure. For this post, we demonstrate the on-demand scale-out functionality.
Modify the thresholds to match your MSK broker instance size and business requirements by editing src/config/on_demand_scaling_config.json. Refer to the configuration documentation for more details of the configuration options available. By default, on_demand_scaling_config.json considers the express.m7g.large broker instance size. Therefore the scale-in/scale-out ingress/egress thresholds are configured at 70% of the recommended sustained throughput for the instance size.
Bootstrap your environment for use with the AWS CDK.
The monitoring_frequency_minutes parameter controls how often the EventBridge scheduler invokes the scaling logic Lambda function to evaluate cluster metrics.
The deployment creates the AWS resources required to run the on-demand scaling solution. The details of the resources created are shown in the output of the command.
Create a Kafka topic in the cluster. Update the following command for the specific authentication method in Amazon MSK. Refer to the Amazon MSK Labs workshop for more details.
Topics should have a sufficient number of partitions that can be distributed across a larger set of brokers.
Generate load on the MSK cluster to trigger and verify the scaling operations. You can use an existing application that drives load to your cluster. You can also use the kafka-producer-perf-test.sh utility that is bundled as part of the Kafka distribution to generate load:
Monitor the scaling operations by tailing the Lambda function logs:
aws logs tail /aws/lambda/MSKOnDemandScalingStack-MSKScalingFunction  \
--follow --format short
In the logs, look for the following messages to identify the exact times when scaling operations occurred. The log statements above these messages show the rationale behind the scaling decision:
The solution also creates a CloudWatch dashboard that provides visibility into scaling operations and many other broker metrics. The link to the dashboard is shown in the output of the cdk deploy command.
The following figure shows a cluster that started with three brokers. After the 09:15 mark, it received consistent inbound traffic, which exceeded the thresholds set in the solution. The solution added three more brokers that came into service at around the 09:45 mark. Intelligent rebalancing reassigned some of the partitions to the newly added brokers and the incoming traffic was split across six brokers. The solution continued adding more brokers until the cluster had 12 brokers and the intelligent rebalancing feature continued distributing the partitions across the newly added brokers.
The following figure shows the times when partition rebalancing was active (value=1). In the context of this solution, that typically occurs after new brokers are added or removed and the scaling operations are complete.
The following figure shows the number of brokers added (positive values) or removed (negative values) from the cluster. This helps visualize and track the size of the cluster as it goes through scaling operations.
Scheduled scaling solution
The scheduled scaling implementation supports timing patterns through an EventBridge schedule. You can configure timing to trigger an action using cron expressions. Based on the cron expression, the EventBridge Scheduler triggers a Lambda function at the specified time to scale out or scale in. The Lambda function performs checks if the cluster is ready for a scaling operation and performs the requested scaling operation by invoking the Amazon MSK control plane API. The service allows removing only three brokers at a time from a cluster. The solution handles this scenario by repeatedly removing the brokers in counts of three until the desired number of brokers are reached.
The following diagram illustrates the architecture of the scheduled scaling solution.
Configuration parameters
EventBridge schedules support cron expressions for precise timing control, so you can fine-tune scaling operations for specific times of day and days of the week. For example, you can configure scaling to occur at 8:00 AM on weekdays using the cron expression cron(0 8 ? * MON-FRI *). To scale in at 6:00 PM on the same days, use cron(0 18 ? * MON-FRI *). For more patterns, refer to Setting a schedule pattern for scheduled rules (legacy) in Amazon EventBridge. You can also configure the desired broker count to be reached during scale-out and scale-in operations.
Deploy scheduled scaling solution
Follow these steps to deploy the scheduled scaling solution:
Modify the scaling schedule by editing scaling/cdk/src/config/scheduled_scaling_config.json. Refer to the configuration documentation for more details of the configuration options available.
Deploy the scheduled scaling AWS CDK application:
cdk deploy MSKScheduledScalingStack \
    --app "python3 msk_scheduled_scaling_stack.py" \
    --context cluster_arn="<< ARN of the MSK Cluster >>" \
    --context stack_name="MSKScheduledScalingStack"
Test and monitor the scheduled scaling solution
The scheduled scaling is triggered as specified in the EventBridge Scheduler cron. However, if you want to test the scale-out operations, run the following command to manually invoke the Lambda function:
Monitor the scaling operations by tailing the Lambda function logs:
aws logs tail /aws/lambda/MSKScheduledScalingStack-MSKScheduledScalingFunction  \
--follow --format short
You can monitor scheduled scaling using the CloudWatch dashboard as described in the on-demand scaling section.
Review scaling configuration parameters
The configuration parameters for both on-demand and scheduled scaling are documented in Configuration Options. These configurations give you flexibility to change how and when the scaling happens. It is important to go through the configuration parameters and make sure they meet your business requirement. For on-demand scaling, you can scale the cluster based on built-in performance metrics or custom metrics (for example MessagesInPerSec).
Considerations
Keep in mind the following considerations when deploying either solution:
EventBridge notifications for scaling failures – Both on-demand and scheduled scaling solutions publish EventBridge notifications when scaling operations fail. Create EventBridge rules to route these failure events to your monitoring and alerting system to detect failures in scaling and respond to them. For details on event sources, types, and payloads, refer to the EventBridge notifications section in the GitHub repo.
Cool-down period management – Properly configure cool-down periods to prevent scaling oscillations where the cluster repeatedly scales out and scales in rapidly. Oscillations typically occur when traffic patterns have short-term spikes that don’t represent sustained demand. Oscillations can also happen when thresholds are set too close to normal operating levels. Set cool-down periods based on your workload characteristics and the scaling completion times. Also consider different cool-down periods for scale-out vs. scale-in operations by setting longer cool-down periods for scale-in operations (scale_in_cooldown_minutes) compared to scaling out (scale_out_cooldown_minutes). Test cool-down settings under realistic load patterns before production deployment to achieve optimal performance.
Cost control through monitoring frequency – The solution incurs costs for services like Lambda functions, EventBridge schedules, CloudWatch metrics, and logs that are used in the solution. Both on-demand and scheduled scaling solutions work by running periodically to check the cluster health status and if a scaling operation needs to be performed. The default 1-minute monitoring frequency provides responsive scaling but increases other costs associated with the solution. Consider increasing the monitoring interval based on your workload characteristics to balance scaling responsiveness and the cost incurred by the solution. You can change the monitoring frequency by changing the monitoring_frequency_minutes when you deploy the solution.
Solution isolation – The on-demand and scheduled scaling solutions were designed and tested in isolation to support predictable behavior and optimal performance. You can deploy either solution, but avoid running both solutions simultaneously on the same cluster. Using both approaches together can cause unpredictable scaling behavior where the solutions might conflict with each other’s scaling decisions, leading to resource contention and potential scaling oscillations. Choose the approach that best matches your workload patterns and deploy only one scaling solution per cluster.
Clean up
Follow these steps to delete the resources created by the solution. Make sure all the scaling operations that are in flight are completed before you run the cleanup.Delete the on-demand scaling solution with the following code:
In this post, we showed how to use intelligent rebalancing to scale your Express based cluster based on your business requirements without requiring manual partition rebalancing. You can extend the solution to use the specific CloudWatch metrics that your business depends on to dynamically scale your Kafka cluster. Similarly, you can adjust the scheduled scaling solution to scale out and scale in your cluster when you anticipate significant change in traffic to your cluster at specific times.To learn more about the services used in this solution, refer to the following resources:
Customers migrating from on-premises Oracle databases to AWS face a challenge: efficiently relocating large object data types (LOBs) to object storage while maintaining data integrity and performance. This challenge originates from the traditional enterprise database design where LOBs are stored alongside structured data, leading to storage capacity constraints, backup complexity, and performance bottlenecks during data retrieval and processing. LOBs, which can include images, videos, and other large files, often cause traditional data migrations to suffer from slow speeds and LOB truncation issues. These issues are particularly problematic for long-running migrations that can span several years.
In this post, we present a scalable solution that uses Amazon Managed Streaming for Apache Kafka (Amazon MSK), Amazon Aurora PostgreSQL-Compatible Edition, and Amazon MSK Connect. The data streaming enables data replication where modifications are sent and received in a continuous flow, allowing the target database to access and apply the changes in real time. This solution generates events for database actions such as insert, update, and delete, triggering AWS Lambda functions to download LOBs from the source Oracle database and upload them to Amazon Simple Storage Service (Amazon S3) buckets. Simultaneously, the streaming events migrate the structured data from the Oracle database to the target database while maintaining proper linking with their respective LOBs.
The complete implementation is available on GitHub, including AWS Cloud Development Kit (AWS CDK) deployment code, configuration files, and setup instructions.
Solution overview
Although traditional Oracle database migrations handle structured data effectively, they struggle with LOBs that can include images, videos, and documents. These migrations often fail due to size limitations and truncation issues, creating significant business risks, including data loss, extended downtime, and project delays that can force you to delay your cloud transformation initiatives. The problem becomes more acute during long-running migrations spanning several years, where maintaining operational continuity is critical. This solution addresses the key challenges of LOB migration, enabling continuous, long-term operations without compromising performance or reliability.
By removing the size limitations associated with traditional migration technologies, our solution provides a robust framework that helps you seamlessly relocate LOBs while facilitating data integrity throughout the process.
Our approach uses a modern streaming architecture to alleviate the traditional constraints of Oracle LOB migration. The solution includes the following core components:
Amazon MSK – Provides the streaming infrastructure.
Amazon MSK Connect – Using two connectors:
Debezium Connector for Oracle as a source connector to capture row-level changes that occur in Oracle database. The connector emits change events and publishes to a Kafka source topic.
Debezium Connector for JDBC as a sink connector to consume events from Kafka source topic and then write those events to Aurora PostgreSQL-Compatible by using a JDBC driver.
Lambda function – Triggered by an event source mapping to Amazon MSK. The function processes events from the Kafka source topic, extracting the Oracle row primary key from each event payload. It uses this key to download the corresponding BLOB data from the source Oracle database and uploads it to Amazon S3, organizing files by primary key folders to maintain simple linking with the relational database records.
Aurora PostgreSQL-Compatible – Used as the target database for migrated data.
Amazon S3 – Used as object storage for storing the BLOB data from source database.
The following diagram shows the Oracle LOB data migration architecture solution.
Message flow
When data changes occur in the source Amazon RDS for Oracle database, the solution executes the following sequence, moving through event detection and publication, BLOB processing with Lambda, and structured data processing:
The Oracle source connector captures the change data capture (CDC) events, including the change to BLOB data column. This connector configures the BLOB data column to exclude from the Kafka event to optimize the Kafka payload.
The connector publishes this event to an MSK topic.
The MSK event triggers the BLOB Downloader Lambda function for the CDC events.
The Lambda function examines two key conditions: the Debezium event code (specifically checking for create (c) or update(u)) and the configured list of Oracle BLOB table names along with their column names. When a Kafka message matches both the configured table list and valid Debezium events, the Lambda function initiates the BLOB data download from the Oracle source using the primary key and table name; otherwise, the function bypasses the BLOB download process. This selective approach makes sure the Lambda function only executes SQL queries when processing Kafka messages for tables containing BLOB data, optimizing database interactions.
The Lambda function uploads the BLOB to Amazon S3, organizing by primary key folders with unique object names, which enables linking between structured database records and their corresponding BLOB data in Amazon S3.
The PostgreSQL sink connector receives the event from the MSK topic.
The connector applies these changes to the Aurora PostgreSQL database for the Oracle database changes except the BLOB data column. The BLOB data column is excluded by the Oracle source connector.
Key benefits
The solution offers the following key advantages:
Cost optimization and licensing – Our approach offers significant cost optimization benefits by reducing the overall size of your database and alleviating your need for expensive licenses associated with traditional databases and replication technologies. By decoupling LOB storage from the database and using Amazon S3, you can reduce your overall database footprint and reduce costs associated with traditional licensing and replication technologies. The streaming architecture also minimizes your infrastructure overhead during long-running migrations.
Avoids size constraints and migration failures – Traditional migration tools often impose size limitations on LOB transfers, leading to truncation issues and failed migrations. This solution removes those constraints entirely, so you can migrate LOBs of different sizes while maintaining data integrity. The event-driven architecture enables near real-time data replication, allowing your source systems to remain operational during migration.
Business continuity and operational excellence – Changes flow continuously to your target environment, allowing for business continuity. The solution preserves relationships between structured database records and their corresponding LOBs through primary key-based organization in Amazon S3, allowing for referential integrity while providing the flexibility of object storage for large files.
Architectural advantages – Storing LOBs in Amazon S3 while maintaining structured data in Aurora PostgreSQL-Compatible creates a clear separation. This architecture simplifies your backup and recovery operations, improves query performance on structured data, and provides flexible access patterns for binary objects through Amazon S3.
Implementation best practices
Consider the following best practices when implementing this solution:
Start small and scale gradually – To implement this solution, start with a pilot project using non-production data to validate your approach before committing to full-scale migration. This gives you a chance to work out issues in a controlled environment and refine your configuration without impacting production systems.
Monitoring – Set up comprehensive monitoring through Amazon CloudWatch to track key metrics like Kafka lag, Lambda function errors, and replication latency. Establish alerting thresholds early so you can catch and resolve issues quickly before they impact your migration timeline. Size your MSK cluster based on expected CDC volume and configure Lambda reserved concurrency to handle peak loads during initial data synchronization.
Security – For security, use encryption in transit and at rest for both structured data and LOBs, and follow the principle of least privilege when setting up AWS Identity and Access Management (IAM) roles and policies for your MSK cluster, Lambda functions, S3 buckets, and database instances. Document your schema mappings between Oracle and Aurora PostgreSQL-Compatible, including how database records link to their corresponding LOBs in Amazon S3.
Testing and preparation – Before you go live, test your failover and recovery procedures thoroughly. Validate scenarios like Lambda function failures, MSK cluster issues, and network connectivity problems to ensure you’re prepared for potential issues. Finally, remember that this streaming architecture maintains eventual consistency between your source and target systems, so there might be brief lag times during high-volume periods. Plan your cutover strategy with this in mind.
Limitations and considerations
Although this solution provides a robust approach for migrating Oracle databases with LOBs to AWS, there are several inherent constraints to understand before implementation.
This solution requires network connectivity between your source Oracle database and AWS environment. For on-premises Oracle databases, you must establish AWS Direct Connect or VPN connectivity before deployment. Network bandwidth directly impacts replication speed and overall migration performance, so your connection must be able to handle the expected volume of CDC events and LOB transfers.
The solution uses Debezium Connector for Oracle as the source connector and Debezium Connector for JDBC as the sink connector. This architecture is specifically designed for your Oracle-to-PostgreSQL migrations. Other database combinations require different connector configurations or might not be supported by the current implementation. Migration throughput is also constrained by your MSK cluster capacity and Lambda concurrency limits. You can also exceed AWS service quotas for large-scale migrations and you might need to request quota increases through AWS Enterprise Support.
Conclusion
In this post, we presented a solution that addresses the critical challenge of migrating your large binary objects from Oracle to AWS by using a streaming architecture that separates LOB storage from structured data. This approach avoids size constraints, reduces Oracle licensing costs, and preserves data integrity throughout extended migration periods.
Ready to transform your Oracle migration strategy? Visit the GitHub repository, where you will find the complete AWS CDK deployment code, configuration files, and step-by-step instructions to get started.
This is a guest post by Oleh Khoruzhenko, Senior Staff DevOps Engineer at Bazaarvoice, in partnership with AWS.
Bazaarvoice is an Austin-based company powering a world-leading reviews and ratings platform. Our system processes billions of consumer interactions through ratings, reviews, images, and videos, helping brands and retailers build shopper confidence and drive sales by using authentic user-generated content (UGC) across the customer journey. The Bazaarvoice Trust Mark is the gold standard in authenticity.
Apache Kafka is one of the core components of our infrastructure, enabling real-time data streaming for the global review platform. Although Kafka’s distributed architecture met our needs for high-throughput, fault-tolerant streaming, self-managing this complex system diverted critical engineering resources away from our core product development. Each component of our Kafka infrastructure required specialized expertise, ranging from configuring low-level parameters to maintaining the complex distributed systems that our customers rely on. The dynamic nature of our environment demanded continuous care and investment in automation. We found ourselves constantly managing upgrades, applying security patches, implementing fixes, and addressing scaling needs as our data volumes grew.
In this post, we show you the steps we took to migrate our workloads from self-hosted Kafka to Amazon Managed Streaming for Apache Kafka (Amazon MSK). We walk you through our migration process and highlight the improvements we achieved after this transition. We show how we minimized operational overhead, enhanced our security and compliance posture, automated key processes, and built a more resilient platform while maintaining the high performance our global customer base expects.
The need for modernization
As our platform grew to process billions of daily consumer interactions, we needed to find a way to scale our Kafka clusters efficiently while maintaining a small team to manage the infrastructure. The limitations of self-managed Kafka clusters manifested in several key areas:
Scaling operations – Although scaling our self-hosted Kafka clusters wasn’t inherently complex, it required careful planning and execution. Each time we needed to add new brokers to handle increased workload, our team faced a multi-step process involving capacity planning, infrastructure provisioning, and configuration updates.
Configuration complexity – Kafka offers hundreds of configuration parameters. Although we didn’t actively manage all of these, understanding their impact was important. Key settings like I/O threads, memory buffers, and retention policies needed ongoing attention as we scaled. Even minor adjustments could have significant downstream effects, requiring our team to maintain deep expertise in these parameters and their interactions to ensure optimal performance and stability.
Infrastructure management and capacity planning – Self-hosting Kafka required us to manage multiple scaling dimensions, including compute, memory, network throughput, storage throughput, and storage volume. We needed to carefully plan capacity for all these components, often making complex trade-offs. Beyond capacity planning, we were responsible for real-time management of our Kafka infrastructure. This included promptly detecting and addressing component failures and performance issues. Our team needed to be highly responsive to alerts, often requiring immediate action to maintain system stability.
Specialized expertise requirements – Operating Kafka at scale demanded deep technical expertise across multiple domains. The team needed to:
Monitor and analyze hundreds of performance metrics
Conduct complex root cause analysis for performance issues
Manage ZooKeeper ensemble coordination
Execute rolling updates for zero-downtime upgrades and security patches
These challenges were compounded during peak business periods, such as Black Friday and Cyber Monday, when maintaining optimal performance was essential for Bazaarvoice’s retail customers.
Choosing Amazon MSK
After evaluating various options, we selected Amazon MSK as our modernization solution. The decision was driven by the service’s ability to minimize operational overhead, provide high availability out of the box with its three Availability Zone architecture, and offer seamless integration with our existing AWS infrastructure.
Key capabilities that made Amazon MSK the clear choice:
AWS integration – We already used AWS services for data processing and analytics. Amazon MSK connected directly with these services, alleviating the need to build and maintain custom integrations. This meant our existing data pipelines would continue working with minimal changes.
Automated operations management – Amazon MSK automated our most time-consuming tasks. We no longer need to manually monitor instances and storage for failures or respond to these issues ourselves.
Enterprise-grade reliability – The platform’s architecture matched our reliability requirements out of the box. Multi-AZ distribution and built-in replication gave us the same fault tolerance we’d carefully built into our self-hosted system, now backed by AWS’s service guarantees.
Simplified upgrade process – Before Amazon MSK, version upgrades for our Kafka clusters required careful planning and execution. The process was complex, involving multiple steps and risks. Amazon MSK simplified our upgrade operations. We now use automated upgrades for dev and test workloads and maintain control over production environments. This shift reduced the need for extensive planning sessions and multiple engineers. As a result, we stay current with the latest Kafka versions and security patches, improving our system reliability and performance.
Enhanced security controls – Our platform required ISO 27001 compliance, which typically involved months of documentation and security controls implementation. Amazon MSK came with this certification built-in, alleviating the need for separate compliance work. Amazon MSK encrypted our data, controlled network access, and integrated with our existing security tools.
With Amazon MSK selected as our target platform, we began planning the complex task of migrating our critical streaming infrastructure without disrupting the billions of consumer interactions flowing through our system.
Bazaarvoice’s migration journey
Moving our complex Kafka infrastructure to Amazon MSK required careful planning and precise execution. Our platform processes data through two main components: an Apache Kafka Streams pipeline that handles data processing and augmentation, and client applications that move this enriched data to downstream systems. With 40 TB of state across 250 internal topics, this migration demanded a methodical approach.
Planning phase
Working with AWS Solutions Architects proved critical for validating our migration strategy. Our platform’s unique characteristics required special consideration:
Multi-Region deployment across the US and EU
Complex stateful applications with strict data consistency needs
Vital business services requiring zero downtime
Diverse consumer ecosystem with different migration requirements
Migration challenges
The biggest hurdle was migrating our stateful Kafka Streams applications. Our data processing runs as a directed acyclic graph (DAG) of applications across regions, using static group membership to prevent disruptive rebalancing. It’s important to note that Kafka Streams keeps its state in internal Kafka topics. For applications to recover properly, replicating this state accurately is crucial. This characteristic of Kafka Streams added complexity to our migration process. Initially, we considered MirrorMaker2, the standard tool for Kafka migrations. However, two fundamental limitations made it challenging:
Risk of losing state or incorrectly replicating state across our applications.
Inability to run two instances of our applications simultaneously, which meant we needed to shut down the main application and wait for it to recover from the state in the MSK cluster. Given the size of our state, this recovery process exceeded our 30-minute SLA for downtime.
Our solution
We decided to deploy a parallel stack of Kafka Streams applications reading and writing data from Amazon MSK. This approach gave us sufficient time for testing and verification, and enabled the applications to hydrate their state before we delivered the output to our data warehouse for analytics. We used MirrorMaker2 for input topic replication, while our solution offered several advantages:
Simplified monitoring of the replication process
Avoided consistency issues between state stores and internal topics
Allowed for gradual, controlled migration of consumers
Enabled thorough validation before cutover
Required a coordinated transition plan for all consumers, because we couldn’t transfer consumer offsets across clusters
Consumer migration strategy
Each consumer type required a carefully tailored approach:
Standard consumers – For applications supporting Kafka Consumer Group protocol, we implemented a four-step migration. This approach risked some duplicate processing, but our applications were designed to handle this scenario. The steps were as follows:
Configure consumers with auto.offset.reset: latest.
Stop all DAG producers.
Wait for existing consumers to process remaining messages.
Cut over consumer applications to Amazon MSK.
Apache Kafka Connect Sinks – Our sink connectors served two critical databases:
A distributed search and analytics engine – Document versioning depended on Kafka record offsets, making direct migration impossible. To address this, we implemented a solution that involved building new search engine clusters from scratch.
A document-oriented NoSQL database – This supported direct migration without requiring new database instances, simplifying the process significantly.
Apache Spark and Flink applications – These presented unique challenges due to their internal checkpointing mechanisms:
Offsets managed outside Kafka’s consumer groups
Checkpoints incompatible between source and target clusters
Required complete data reprocessing from the beginning
We scheduled these migrations during off-peak hours to minimize impact.
Technical benefits and improvements
Moving to Amazon MSK fundamentally changed how we manage our Kafka infrastructure. The transformation is best illustrated by comparing key operational tasks before and after the migration, summarized in the following table.
Activity
Before: Self-Hosted Kafka
After: Amazon MSK
Security patching
Required dedicated team time for Kafka and OS updates
Fully automated
Broker recovery
Needed manual monitoring and intervention
Fully automated
Client authentication
Complex password rotation procedures
AWS Identity and Access Management (IAM)
Version upgrades
Complex procedure requiring extensive planning
Fully automated
The details of the tasks are as follows:
Security patching – Previously, our team spent 8 hours monthly applying Kafka and operating system (OS) security patches across our broker fleet. Amazon MSK now handles these updates automatically, maintaining our security posture without engineering intervention.
Broker recovery – Although our self-hosted Kafka had automatic recovery capabilities, each incident required careful monitoring and occasional manual intervention. With Amazon MSK, node failures and storage degradation issues such as Amazon Elastic Block Store (Amazon EBS) slowdowns are handled entirely by AWS and resolved within minutes without our involvement.
Authentication management – Our self-hosted implementation required password rotations for SASL/SCRAM authentication, a process that took two engineers several days to coordinate. The direct integration between Amazon MSK and AWS Identity and Access Management (IAM) minimized this overhead while strengthening our security controls.
Version upgrades – Kafka version upgrades in our self-hosted environment required weeks of planning and testing as well as weekend maintenance windows. Amazon MSK manages these upgrades automatically during off-peak hours, maintaining our SLAs without disruption.
These improvements proved especially valuable during high-traffic periods like Black Friday, when our team previously needed extensive operational readiness plans. Now, the built-in resiliency of Amazon MSK provides us with reliable Kafka clusters that serve as mission-critical infrastructure for our business. The migration made it possible to break our monolithic clusters into smaller, dedicated MSK clusters. This improved our data isolation, provided better resource allocation, and enhanced performance predictability for high-priority workloads.
Lessons learned
Our migration to Amazon MSK revealed several key insights that can help other organizations modernize their Kafka infrastructure:
Expert validation – Working with AWS Solutions Architects to validate our migration strategy caught several critical issues early. Although our team knew our applications well, external Kafka experts identified potential problems with state management and consumer offset handling that we hadn’t considered. This validation prevented costly missteps during the migration.
Data verification – Comparing data across Kafka clusters proved challenging. We built tools to capture topic snapshots in Parquet format on Amazon Simple Storage Service (Amazon S3), enabling quick comparisons using Amazon Athena queries. This approach gave us confidence that data remained consistent throughout the migration.
Start small – Beginning with our smallest data universe in QA helped us refine our process. Each subsequent migration went smoother as we applied lessons from previous iterations. This gradual approach helped us maintain system stability while building team confidence.
Detailed planning – We created specific migration plans with each team, considering their unique requirements and constraints. For example, our machine learning pipeline needed special handling due to strict offset management requirements. This granular planning prevented downstream disruptions.
Performance optimization – We found that utilizing Amazon MSK provisioned throughput offered clear cost advantages when storage throughput became a bottleneck. This feature made it possible to improve cluster performance without scaling instance sizes or adding brokers, providing a more efficient solution to our throughput challenges.
Documentation – Maintaining detailed migration runbooks proved invaluable. When we encountered similar issues across different migrations, having documented solutions saved significant troubleshooting time.
Conclusion
In this post, we showed you how we modernized our Kafka infrastructure by migrating to Amazon MSK. We walked through our decision-making process, challenges faced, and strategies employed. Our journey transformed Kafka operations from a resource-intensive, self-managed infrastructure to a streamlined, managed service, improving operational efficiency, platform reliability, and team productivity. For enterprises managing self-hosted Kafka infrastructure, our experience demonstrates that successful transformation is achievable with proper planning and execution. As data streaming needs grow, modernizing infrastructure becomes a strategic imperative for maintaining competitive advantage.
For more information, visit the Amazon MSK product page, and explore the comprehensive Developer Guide to learn about the features available to help you build scalable and reliable streaming data applications on AWS.
In this post, we show you how to implement real-time data ingestion from multiple Kafka topics to Apache Hudi tables using Amazon EMR. This solution streamlines data ingestion by processing multiple Amazon Managed Streaming for Apache Kafka (Amazon MSK) topics in parallel while providing data quality and scalability through change data capture (CDC) and Apache Hudi.
Organizations processing real-time data changes across multiple sources often struggle with maintaining data consistency and managing resource costs. Traditional batch processing requires reprocessing entire datasets, leading to high resource usage and delayed analytics. By implementing CDC with Apache Hudi’s MultiTable DeltaStreamer, you can achieve real-time updates; efficient incremental processing with atomicity, consistency, isolation, durability (ACID) guarantees; and seamless schema evolution while minimizing storage and compute costs.
Using Amazon Simple Storage Service (Amazon S3), Amazon CloudWatch, Amazon EMR, Amazon MSK and AWS GlueData Catalog, you’ll build a production-ready data pipeline that processes changes from multiple data sources simultaneously. Through this tutorial, you’ll learn to configure CDC pipelines, manage table-specific configurations, implement 15-minute sync intervals, and maintain your streaming pipeline. The result is a robust system that maintains data consistency while enabling real-time analytics and efficient resource utilization.
What is CDC?
Imagine a constantly evolving data stream, a river of information where updates flow continuously. CDC acts like a sophisticated net, capturing only the modifications—the inserts, updates, and deletes—happening within that data stream. Through this targeted approach, you can focus on the new and changed data, significantly improving the efficiency of your data pipelines.There are numerous advantages to embracing CDC:
Reduced processing time – Why reprocess the entire dataset when you can focus only on the updates? CDC minimizes processing overhead, saving valuable time and resources.
Real-time insights – With CDC, your data pipelines become more responsive. You can react to changes almost instantaneously, enabling real-time analytics and decision-making.
Simplified data pipelines – Traditional batch processing can lead to complex pipelines. CDC streamlines the process, making data pipelines more manageable and easier to maintain.
Why Apache Hudi?
Hudi simplifies incremental data processing and data pipeline development. This framework efficiently manages business requirements such as data lifecycle and improves data quality. You can use Hudi to manage data at the record-level in Amazon S3 data lakes to simplify CDC and streaming data ingestion and handle data privacy use cases requiring record-level updates and deletes. Datasets managed by Hudi are stored in Amazon S3 using open storage formats, while integrations with Presto, Apache Hive, Apache Spark, and Data Catalog give you near real time access to updated data. Apache Hudi facilitates incremental data processing for Amazon S3 by:
Managing record-level changes – Ideal for update and delete use cases
Open formats – Integrates with Presto, Hive, Spark, and Data Catalog
HoodieMultiTableDeltaStreamer – Simplifies ingestion into multiple tables using centralized configurations
Hudi MultiTable Delta Streamer
The HoodieMultiTableStreamer offers a streamlined approach to data ingestion from multiple sources into Hudi tables. By processing multiple sources simultaneously through a single DeltaStreamer job, it eliminates the need for separate pipelines while reducing operational complexity. The framework provides flexible configuration options, and you can tailor settings for diverse formats and schemas across different data sources.
One of its key strengths lies in unified data delivery, organizing information in respective Hudi tables for seamless access. The system’s intelligent upsert capabilities efficiently handle both inserts and updates, maintaining data consistency across your pipeline. Additionally, its robust schema evolution support enables your data pipeline to adapt to changing business requirements without disruption, making it an ideal solution for dynamic data environments.
Solution overview
In this section, we show how to stream data to Apache Hudi Table using Amazon MSK. For this example scenario, there are data streams from three distinct sources residing in separate Kafka topics. We aim to implement a streaming pipeline that uses the Hudi DeltaStreamer with multitable support to ingest and process this data at 15-minute intervals.
Mechanism
Using MSK Connect, data from multiple sources flows into MSK topics. These topics are then ingested into Hudi tables using the Hudi MultiTable DeltaStreamer. In this sample implementation, we create three Amazon MSK topics and configure the pipeline to process data in JSON format using JsonKafkaSource, with the flexibility to handle Avro format when needed through the appropriate deserializer configuration
The following diagram illustrates how our solution processes data from multiple source databases through Amazon MSK and Apache Hudi to enable analytics in Amazon Athena. Source databases send their data changes—including inserts, updates, and deletes—to dedicated topics in Amazon MSK, where each data source maintains its own Kafka topic for change events. An Amazon EMR cluster runs the Apache Hudi MultiTable DeltaStreamer, which processes these multiple Kafka topics in parallel, transforming the data and writing it to Apache Hudi tables stored in Amazon S3. Data Catalog maintains the metadata for these tables, enabling seamless integration with analytics tools. Finally, Amazon Athena provides SQL query capabilities on the Hudi tables, allowing analysts to run both snapshot and incremental queries on the latest data. This architecture scales horizontally as new data sources are added, with each source getting its dedicated Kafka topic and Hudi table configuration, while maintaining data consistency and ACID guarantees across the entire pipeline.
To set up the solution, you need to complete the following high-level steps:
Set up Amazon MSK and create Kafka topics
Create the Kafka topics
Create table-specific configurations
Launch Amazon EMR cluster
Invoke the Hudi MultiTable DeltaStreamer
Verify and query data
Prerequisites
To perform the solution, you need to have the following prerequisites. For AWS services and permissions, you need:
The Hudi MultiTable DeltaStreamer configuration is divided into two major components to streamline and standardize data ingestion:
Common configurations – These settings apply across all tables and define the shared properties for ingestion. They include details such as shuffle parallelism, Kafka brokers, and common ingestion configurations for all topics.
Table-specific configurations – Each table has unique requirements, such as the record key, schema file paths, and topic names. These configurations tailor each table’s ingestion process to its schema and data structure.
Create common configuration file
Common Config: kafka-hudi config file where we specify kafka broker and common configuration for all topics as below
Create the kafka-hudi-deltastreamer.properties file with the following properties:
These configurations form the backbone of Hudi’s ingestion pipeline, enabling efficient data handling and maintaining real-time consistency. Schema configurations define the structure of both source and target data, maintaining seamless data transformation and ingestion. Operational settings control how data is uniquely identified, updated, and processed incrementally.
The following are critical details for setting up Hudi ingestion pipelines:
hoodie.deltastreamer.schemaprovider.source.schema.file – The schema of the source record
hoodie.deltastreamer.schemaprovider.target.schema.file – The schema for the target record
hoodie.deltastreamer.source.kafka.topic – The source MSK topic name
bootstap.servers – The Amazon MSK bootstrap server’s private endpoint
auto.offset.reset – The consumer’s behavior when there is no committed position or when an offset is out of range
Key operational fields to achieve in-place updates for the generated schema include:
hoodie.datasource.write.recordkey.field – The record key field. This is the unique identifier of a record in Hudi.
hoodie.datasource.write.precombine.field – When two records have the same record key value, Apache Hudi picks the one with the largest value for the pre-combined field.
hoodie.datasource.write.operation – The operation on the Hudi dataset. Possible values include UPSERT, INSERT, and BULK_INSERT.
Launch Amazon EMR cluster
This step creates an EMR cluster with Apache Hudi installed. The cluster will run the MultiTable DeltaStreamer to process data from your Kafka topics. To create the EMR cluster, enter the following:
This step configures and starts the DeltaStreamer job that will continuously process data from your Kafka topics into Hudi tables. Complete the following steps:
Connect to the Amazon EMR master node:
# Get master node public DNS
MASTER_DNS=$(aws emr describe-cluster --cluster-id $CLUSTER_ID --query 'Cluster.MasterPublicDnsName' --output text)

# SSH to master node
ssh -i myKey.pem hadoop@$MASTER_DNS
For continuous mode, you need to add the following property:
--continuous \
--min-sync-interval-seconds 900
With the job configured and running on Amazon EMR, the Hudi MultiTable DeltaStreamer efficiently manages real-time data ingestion into your Amazon S3 data lake.
Verify and query data
To verify and query the data, complete the following steps:
Register tables in Data Catalog:
# Start Spark shell
spark-shell --conf "spark.serializer=org.apache.spark.serializer.KryoSerializer" \
  --conf "spark.sql.catalog.spark_catalog=org.apache.spark.sql.hudi.catalog.HoodieCatalog" \
  --conf "spark.sql.extensions=org.apache.spark.sql.hudi.HoodieSparkSessionExtension" \
  --jars "/usr/lib/hudi/hudi-spark-bundle.jar"

# In Spark shell
spark.sql("CREATE DATABASE IF NOT EXISTS hudi_sales_tables")

spark.sql("""
CREATE TABLE hudi_sales_tables.cust_sales_details
USING hudi
LOCATION 's3://hudi-data-bucket-$AWS_ACCOUNT_ID/hudi/hudi_sales_tables.cust_sales_details'
""")

# Repeat for other tables
Query with Athena:
-- Sample query
SELECT * FROM hudi_sales_tables.cust_sales_details LIMIT 10;
You can use Amazon CloudWatch alarms to alert you of issues with the EMR job or data processing. To create a CloudWatch alarm to monitor EMR job failures, enter the following:
With the pipeline configured and running, you can achieve real-time updates to your data lake, enabling faster analytics and decision-making. For instance:
Analytics – Up-to-date inventory data maintains accurate dashboards for ecommerce platforms.
Monitoring – CloudWatch metrics confirm the pipeline’s health and efficiency.
Flexibility – The seamless handling of schema evolution minimizes downtime and data inconsistencies.
Cleanup
To avoid incurring future charges, follow these steps to clean up resources:
In this post, we showed how you can build a scalable data ingestion pipeline using Apache Hudi’s MultiTable DeltaStreamer on Amazon EMR to process data from multiple Amazon MSK topics. You learned how to configure CDC with Apache Hudi, set up real-time data processing with 15-minute sync intervals, and maintain data consistency across multiple sources in your Amazon S3 data lake.
By combining CDC with Apache Hudi, you can build efficient, real-time data pipelines. The streamlined ingestion processes simplify management, enhance scalability, and maintain data quality, making this approach a cornerstone of modern data architectures.
Managing and scaling data streams efficiently is a cornerstone of success for many organizations. Apache Kafka is a leading platform for real-time data streaming, offering unmatched scalability and reliability. However, setting up and scaling Kafka clusters can be challenging, requiring significant time, expertise, and resources. Amazon Managed Streaming for Apache Kafka (MSK) helps you build and run production applications on Apache Kafka without needing Kafka infrastructure management expertise or having to deal with the complex overhead associated with setting up and running Apache Kafka on your own.
Amazon MSK Provisioned supports both Standard brokers and Express brokers. Express brokers are designed for higher throughput, faster scalability, and lower operational overhead, while Standard brokers offer more granular control and configuration flexibility. While Amazon MSK significantly reduces cluster management overhead, teams still perform routine tasks such as topic management, partition management, and implementing specific configurations to meet their business requirements.
To further simplify these day-to-day operations, you can use Kiro Command Line Interface (CLI) along with the MSK Model Context Protocol (MCP) server for a more intuitive approach to cluster management. These tools enable teams to perform administrative tasks and operational activities using natural language commands. Whether you’re managing topics, monitoring cluster health, or implementing specific configurations, the ability to use plain English commands makes these tasks more accessible to both experienced administrators and developers new to Kafka.
In this post, we demonstrate how Kiro CLI and the MSK MCP server can streamline your Kafka management. Through practical examples and demonstrations, we show you how to use these tools to perform common administrative tasks efficiently while maintaining robust security and reliability.
Understanding the Model Context Protocol advantage
The MCP is an emerging open standard that defines how artificial intelligence (AI) agents can securely access and interact with external tools, data sources, and services. Rather than requiring developers learn intricate API syntax across multiple services, MCP enables AI assistants to understand your environment contextually and provide intelligent guidance. A Kiro CLI agent is an AI-powered assistant in the command-line interface that understands your code and environment to execute tasks, generate code, and automate workflows through natural language interactions. Together, Kiro CLI and the Model Context Protocol (MCP) enable teams to manage their MSK clusters using natural language, making cluster administration more intuitive and accessible.
The Amazon MSK MCP Server provides essential cluster administration capabilities including describing clusters, updating configurations, and monitoring broker health status. By combining these capabilities with Kiro CLI’s ability to interact with native Kafka command-line tools, teams gain comprehensive visibility into their Apache Kafka environment. Through this unified approach, users can manage both control plane operations via the MCP server and data plane operations, like topic management, through Kiro CLI’s interface with Kafka tools. This integration enables teams to monitor, manage, and optimize their clusters through conversational interactions while maintaining enterprise-grade security through AWS Identity and Access Management (IAM) and fine-grained access controls.
Prerequisites
For this walkthrough, you should have the following prerequisites:
An AWS account – If you don’t have an account, you can create one.
AWS CLI installed and configured on your computer.
Amazon MSK cluster. You could use this Amazon CloudFormation template to deploy one if you done have one already in your account.
Configure Kiro CLI with Amazon MSK MCP server
Installation and configuration The following section covers the steps required to install and configure Amazon MSK MCP server.
Install required dependencies Complete the following steps to install required dependencies:
Install the uv package manager if you haven’t already:
# macOS/Linux
curl -LsSf  | sh

# Windows
powershell -c "irm  | iex“
Install Python 3.10 or newer:
uv python install 3.10
Configure the MCP server Complete the following instructions to set up Kiro CLI on your host machine and access the Amazon MSK MCP server. Configure the Amazon MSK MCP server in your Kiro CLI configuration. Edit the MCP configuration file at ~/.aws/.kiro/mcp.json:
MacOS Installation
For MacOS, the mcp.json file should be as follows:
For further details on installation, refer to the Installation section in the Amazon MSK MCP server README.md.
Start Kiro CLI to verify the MCP server is properly configured using the following command: kiro-cli
Once logged into Kiro CLI, type the following command to check all the MSK mcp server tools are available as shown in the following screenshot: /tools
Installing and configuring Kafka CLI
To perform data plane operations on your Amazon MSK cluster, you need the Kafka command-line tools configured correctly. In the following video demonstration, we show how developers and administrators can use Kiro CLI to streamline the installation and configuration of Kafka command-line tools, enabling seamless interaction with their MSK cluster through natural language commands.
Evaluate cluster best practices
Maintaining a healthy and efficient Apache Kafka cluster requires adherence to established best practices, from proper replication factors to optimal resource utilization. Amazon MSK implements many of these best practices by default, but ongoing monitoring and adjustment are essential for production workloads. In the following demonstration, we show how Kiro CLI can help you evaluate your cluster’s configuration against recommended best practices, identify potential issues, and receive actionable recommendations for optimization. Watch the following demo video as we use natural language queries to assess MSK clusters against AWS recommended best practices and identify topics with replication factors not configured according to best practices and fix them.
Responding to health notifications: Optimizing topic configurations for high availability
Amazon MSK’s health notifications serve as crucial alerts to maintain optimal cluster performance and reliability. For customers using MSK Provisioned with Standard brokers, they may receive notifications about critical configuration parameters such as MinISR and replication factor settings that could impact application resilience. In this section, we demonstrate how Kiro CLI can help you quickly respond to a health notification regarding MinISR (Minimum In-Sync Replicas) and replication factor configurations. Watch as we use natural language commands to identify topics with suboptimal settings, understand their current configurations, and implement the recommended changes to confirm high availability during infrastructure maintenance or recovery events. This real-world scenario showcases how Kiro CLI simplifies the process of maintaining robust Kafka operations while following AWS best practices.
Managing cluster-level configurations: Streamlining parameter updates with natural language
Apache Kafka clusters often require configuration adjustments to meet specific security requirements and use cases. While Amazon MSK provides default configurations, there are situations when you need to customize security parameters like allow.everyone.if.no.acl.found to implement proper access controls and strengthen your cluster’s security posture. In this demonstration, we show how Kiro CLI with MSK MCP server simplifies the process of updating cluster-level configurations.
Instead of opening multiple CLI commands or console screens, you see how natural language instructions can be used to understand current security settings, evaluate the impact of changes, and implement configuration updates seamlessly across your MSK cluster. By setting allow.everyone.if.no.acl.found to false, we confirm that explicit ACL permissions are required for all operations, enhancing the security of your Kafka deployment.
Conclusion
In this post, we demonstrated how Kiro CLI and MSK MCP server make Apache Kafka cluster management more accessible through natural language commands. By transforming complex Kafka operations into simple conversational interactions, these tools enable both experienced administrators and newcomers to efficiently manage their MSK clusters. From routine tasks to addressing configuration challenges, this approach reduces operational complexity and allows teams to focus more on developing innovative streaming applications.
About the authors
Kalyan Janaki is Senior Big Data & Analytics Specialist with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS.
Aarjvi Desaiis a Technical Account Manager at Amazon Web Services, based in San Francisco Bay Area, where she helps customers solve cloud challenges and build scalable, reliable solutions. Her areas of focus include cloud technologies, architecture best practices, and operational excellence.
Sandhya Khanderia is Sr. Technical Account Manager and Data analytics specialist. She works with AWS customers and provides ongoing support and technical guidance to help plan and build solutions using best practices and proactively keep customers’ AWS environments operationally healthy.
Ankit Mishra is a Senior Solutions Architect at Amazon Web Services, where he supports healthcare and life sciences customers around the globe. He is passionate about helping organizations design and build secure, scalable, reliable, and cost-effective cloud solutions. Outside of work, Ankit enjoys spending quality time with his young daughters. Feel free to connect with him on LinkedIn.
This post was co-authored by Mike Araujo Principal Engineer at Medidata Solutions.
The life sciences industry is transitioning from fragmented, standalone tools towards integrated, platform-based solutions. Medidata, a Dassault Systèmes company, is building a next-generation data platform that addresses the complex challenges of modern clinical research. In this post, we show you how Medidata created a unified, scalable, real-time data platform that serves thousands of clinical trials worldwide with AWS services, Apache Iceberg, and a modern lakehouse architecture.
Challenges with legacy architecture
As the Medidata clinical data repository expanded, the team recognized the shortcomings of the legacy data solution to provide quality data products to their customers across their growing portfolio of data offerings. Several data tenants began to erode. The following diagram shows Medidata’s legacy extract, transform, and load (ETL) architecture.
Built upon a series of scheduled batch jobs, the legacy system proved ill-equipped to provide a unified view of the data across the entire ecosystem. Batch jobs ran at different intervals, often requiring a sufficient degree of scheduling buffer to make sure upstream jobs completed within the expected window. As the data volume expanded, the jobs and their schedules continued to inflate, introducing a latency window between ingestion and processing for dependent consumers. Different consumers operating from various underlying data services further magnified the problem as pipelines had to be continuously built across a variety of data delivery stacks.
The expanding portfolio of pipelines began to overwhelm existing maintenance operations. With more operations, the opportunity for failure expanded and recovery efforts further complicated. Existing observability systems were inundated with operational data, and identifying the root cause of data quality issues became a multi-day endeavor. Increases in the data volume required scaling considerations across the entire data estate.
Additionally, the proliferation of data pipelines and copies of the data in different technologies and storage systems necessitated expanding access controls with enhanced security features to make sure only the correct users had access to the subset of data to which they were permitted. Making sure access control changes were correctly propagated across all systems added a further layer of complexity to consumers and producers.
Solution overview
With the advent of Clinical Data Studio (Medidata’s unified data management and analytics solution for clinical trials) and Data Connect (Medidata’s data solution for acquiring, transforming, and exchanging electronic health record (EHR) data across healthcare organizations), Medidata introduced a new world of data discovery, analysis, and integration to the life sciences industry powered by open source technologies and hosted on AWS. The following diagram illustrates the solution architecture.
Fragmented batch ETL jobs were replaced by real-time Apache Flink streaming pipelines, an open source, distributed engine for stateful processing, and powered by Amazon Elastic Kubernetes Service (Amazon EKS), a fully managed Kubernetes service. The Flink jobs write to Apache Kafka running in Amazon Managed Apache Kafka (Amazon MSK), a streaming data service that manages Kafka infrastructure and operations, before landing in Iceberg tables backed by the AWS Glue Data Catalog, a centralized metadata repository for data assets. From this collection of Iceberg tables, a central, single source of data is now accessible from a variety of consumers without additional downstream processing, alleviating the need for custom pipelines to satisfy the requirements of downstream consumers. Through these fundamental architectural changes, the team at Medidata solved the issues presented by the legacy solution.
Data availability and consistency
With the introduction of the Flink jobs and Iceberg tables, the team was able to deliver a consistent view of their data across the Medidata data experience. Pipeline latency was reduced from days to minutes, helping Medidata customers realize a 99% performance gain from the data ingestion to the data analytics layers. Due to Iceberg’s interoperability, Medidata users saw the same view of the data regardless of where they viewed that data, minimizing the need for consumer-driven custom pipelines because Iceberg could plug into existing consumers.
Maintenance and durability
Iceberg’s interoperability provided a single copy of the data to satisfy their use cases, so the Medidata team could focus its observation and maintenance efforts on a five-times smaller subset of operations than previously required. Observability was enhanced by tapping into the various metadata components and metrics exposed by Iceberg and the Data Catalog. Quality management transformed from cross-system traces and queries to a single analysis of unified pipelines, with an added benefit of point in time data queries thanks to the Iceberg snapshot feature. Data volume increases are handled with out-of-box scaling supported by the entire infrastructure stack and AWS Glue Iceberg optimization features that include compaction, snapshot retention, and orphan file deletion, which provide a set-and-forget experience for solving a number of common Iceberg frustrations, such as the small file problem, orphan file retention, and query performance.
Security
With Iceberg at the center of its solution architecture, the Medidata team no longer had to spend the time building custom access control layers with enhanced security features at each data integration point. Iceberg on AWS centralizes the authorization layer using familiar systems such as AWS Identity and Access Management (IAM), providing a single and durable control for data access. The data also stays entirely within the Medidata virtual private cloud (VPC), further reducing the opportunity for unintended disclosures.
Conclusion
In this post, we demonstrated how legacy universe of consumer-driven custom ETL pipelines can be replaced with a scalable, high-performant streaming lakehouses. By putting Iceberg on AWS at the center of data operations, you can have a single source of data for your consumers.
Event-driven applications often need to process data in real-time. When you use AWS Lambda to process records from Apache Kafka topics, you frequently encounter two typical requirements: you need to process very high volumes of records in close to real-time, and you want your consumers to have the ability to scale rapidly to handle traffic spikes. Achieving both necessitates understanding how Lambda consumes Kafka streams, where the potential bottlenecks are, and how to optimize configurations for high throughput and best performance.
In this post, we discuss how to optimize Kafka processing with Lambda for both high throughput and predictable scaling. We explore the Lambda’s Kafka Event Source Mappings (ESMs) scaling, optimization techniques available during record consumption, how to use ESM Provisioned Mode for bursty workloads, and which observability metrics you need to use for performance optimization.
The scaling behavior of Kafka ESMs is based on the offset lag. This is a metric indicating the number of records in the topic that have not yet been consumed by the Lambda function. This metric typically grows when producers publish new records faster than consumers process them. As the lag grows, the Lambda service gradually adds more Kafka consumers (also known as pollers) to your ESM. To preserve ordering guarantees, the maximum number of pollers is capped by the number of partitions in the topic. Lambda also scales pollers down automatically when lag decreases.
Each ESM follows a consistent polling workflow: poll -> filter -> batch -> invoke, as shown in the following diagram. Every stage has configurable options that directly affect performance, latency, and cost.
Figure 1. ESM processing workflow.
Polling: Increasing predictability with Provisioned Mode
By default, Kafka ESM uses the on-demand polling mode. In this mode, ESM starts with one poller, automatically adds more pollers when the offset lag grows, and scales the number of pollers down as lag decreases. On-demand mode does not need upfront scaling configuration and is the lowest-cost option for steady workloads. For many applications, this behavior is sufficient: scaling up can take several minutes, but the throughput eventually catches up, and you only pay for the resources you use, such as number of invocations.
However, if your workloads are bursty and latency-sensitive, then on-demand scaling may not be fast enough and can result in a rapidly growing lag. This can be addressed by switching to Provisioned Mode, which gives you more fine-grained control to configure a minimum and maximum number of always-on pollers for your Kafka ESM. These pollers remain connected even when traffic is low, so consumption begins immediately when a spike occurs, and scaling within the configured range is faster and more predictable.
The following diagram shows the performance improvements of using the ESM in Provisioned Mode for bursty workloads. You can see that in on-demand mode it took ESM over 15 minutes to eventually catch up to the new traffic volume, while in Provisioned Mode the ESM handled the traffic increase instantly.
Figure 2. Comparing Kafka ESM on-demand and Provisioned Mode.
Best practices for using Provisioned Mode:
Start small: Provisioned Mode is a paid capability. AWS recommends that for smaller topics (less than 10 partitions) you start with a single provisioned poller to evaluate throughput and observe workload behavior. For larger topics, you can start with a higher number of provisioned pollers to accommodate the baseline consumption. You can adjust this configuration at any time as you learn traffic patterns and refine your performance targets.
Estimate throughput: A single provisioned poller can process up to 5 MB/s of Kafka data. Monitor your average record size and per-record processing time to establish a baseline for minimum and maximum pollers, then validate with real workload metrics.
Set a low floor and flexible ceiling: Choose a minimum number of pollers that makes sure that latency targets are met when a traffic burst occurs, then allow the ESM to scale toward a higher maximum as needed.
Use Provisioned Mode for bursty traffic, strict SLOs, or when backlogs pose downstream risk.
Use on-demand polling mode for steady traffic, flexible latency requirements, or when minimizing cost is the primary objective.
Filtering: Drop irrelevant records early
By default, all records from Kafka are delivered to your Lambda function. This approach is direct and flexible. Your handler code decides which records to process and which to ignore. This default behavior is highly efficient for workloads where nearly all records are valuable.
When you find yourself discarding a large portion of records in your handler code, you can use native ESM filtering capabilities to drop irrelevant records before they reach your function. You can filter early to reduce cost, free up concurrency, increase throughput, and make sure that your Lambda function spends cycles on valuable work only.
The following diagram shows the application of an ESM filter to only process telemetry that meets a specified condition.
Figure 3. ESM filtering configuration.
Batching: Processing more records per invocation
You can batch multiple Kafka records together to process more data per invocation and increase the efficiency of your Lambda functions. Larger batches help you achieve higher throughput and reduce costs by making better use of each invocation run. To get the best results, you should balance batch size and latency targets and adjust the configuration based on your workload’s specific traffic patterns and SLOs.
Lambda gives you two primary controls for configuring ESM batching behavior:
Batch window: This is how long the ESM waits to accumulate records before invoking your function. A shorter window produces smaller batches and more frequent invocations. A longer window (up to 5 minutes) produces larger batches and less frequent invocations.
Batch size: This is the maximum number of records that the ESM can accumulate before invoking your function, up to 10,000.
There’s no single setting that universally works for all workloads. Your optimal configuration depends on workload characteristics such as latency tolerance and record size. AWS recommends starting with the default values and then gradually adjusting the configuration based on your requirements. For example, you can increase the batch size while monitoring function duration, error rates, and end-to-end latency.
The following diagram shows how to configure batch window and size using Terraform:
Figure 4. ESM batch window and batch size configuration with Terraform.
The ESM invokes your function when one of the following three conditions is met:
The batch window elapses.
The accumulated batch reaches the configured maximum batch size.
The accumulated payload approaches the 6 MB maximum invocation payload limit of Lambda.
When using higher batch window values during traffic spikes, you typically see more records-per-batch and longer function invocation durations. This is normal: larger batches can take longer to process. Always interpret the Duration metric in the context of the batch size being processed.
Invoke: Process each batch faster and more efficiently
You control how quickly each batch completes through two main factors: the efficiency of your function code and the compute resources you allocate to your functions. You can improve both to process more records per second, reduce the necessary concurrency, and lower cost.
Optimize your code: Review your function handler code to identify where you can reduce work per record. For example, eliminate redundant serialization, initialize dependencies once during function startup, and consider parallel processing within the handler (where applicable). For performance-critical workloads, you can also choose languages that compile to binary, such as Go or Rust, which typically deliver high performance with lower resource usage.
Tune compute resources: Increasing the memory function allocation proportionally increases vCPU. Use the Lambda PowerTuning tool to find the memory configuration that best balances performance and cost for your workload.
Correlate metrics: As you optimize, monitor Duration and Concurrency. You should see the concurrency drop as duration improves. That correlation confirms that your changes are improving the system throughput and efficiency.
When you combine handler optimizations with early filtering and efficient batching, even small improvements can make your pipeline noticeably faster to operate under load.
Observability drives good decisions
You can’t optimize what you can’t see. To tune your data processing pipeline, use a combination of OffsetLag, function invocation metrics, and Kafka broker metrics to understand your data processing performance. OffsetLag tells you whether your function is keeping up with incoming records, as shown in the following figure. Function metrics such as Duration, Concurrency, Errors, and Throttles show how efficiently your code is processing record batches. If you use Provisioned Mode, then you can use the Provisioned Pollers metric to track the poller capacity.
Figure 5. Kafka consumption observability with Amazon CloudWatch.
Always interpret function duration in the context of batch size. During traffic spikes, you can typically observe both duration and actual batch size increase, which is expected amortization, not a regression. For alerting, monitor lag growth, unexpected drops in invocation rate, and error spikes. With these signals in place, you can detect issues early and tune your configuration with confidence.
A sample step-by-step optimization loop
Establish a clean baseline: Make your handler idempotent and batch-aware, start with a short batch window and moderate batch size. Monitor your ESM and confirm offset lag stays near zero at steady state.
Filter early: Move static checks (record type, version, other custom properties) into ESM filtering and verify invoked counts drop relative to polled counts, proving the filter saves cost and concurrency.
Increase batch size gradually while monitoring the duration, error rates, and latency metrics. Extend the batch window slightly if spikes cause too many invocations.
Speed up the handler: Increase memory for more CPU, reduce per-record I/O, remove redundant serialization, and parallelize safely inside the batch while tracking duration and concurrency metrics together.
Prove spike readiness: Replay realistic surges, monitor offset lag and drain time, and enable Provisioned Mode with a small minimum if recovery takes too long, adjusting with MB/s-per-poller estimates.
Implement alerting: Watch for sustained lag growth, unexpected gaps between polled and invoked, and error spikes tied to partitions or large batches. Always read metrics in context with batch size.
Re-evaluate periodically: Re-measure system throughput, confirm filter effectiveness, and retune batch and memory settings regularly as workloads evolve.
Conclusion
Optimizing Kafka streams processing with AWS Lambda necessitates understanding how ESMs work and tuning consumption components: polling, filtering, batching, and invoking. Filtering redundant records early removes unnecessary work, batching helps you process more records per invocation, and handler optimizations make sure that you make the most of the compute that you allocate. Together, these adjustments let you scale efficiently and keep offset lag under control.
When your workload is bursty, use Provisioned Mode to absorb spikes without long recovery times. With the right alerts on lag, errors, and unexpected polled versus invoked behavior, you can spot problems early and adjust before they impact users. Following this optimization guide gives you a practical way to measure, tune, and revisit your setup as traffic patterns change.
This is a guest post by Umesh Dangat, Senior Principal Engineer for Distributed Services and Systems at Yelp, and Toby Cole, Principle Engineer for Data Processing at Yelp, in partnership with AWS.
Yelp processes massive amounts of user data daily—over 300 million business reviews, 100,000 photo uploads, and countless check-ins. Maintaining sub-minute data freshness with this volume presented a significant challenge for our Data Processing team. Our homegrown data pipeline, built in 2015 using then-modern streaming technologies, scaled effectively for many years. As our business and data needs evolved, we began to encounter new challenges in managing observability and governance across an increasingly complex data ecosystem, prompting the need for a more modern approach. This affected our outage incidents, making it harder to both assess impact and restore service. At the same time, our streaming framework struggled with Kafka for data streaming and permanent data storage. In addition, our connectors to analytical data stores experienced latencies exceeding 18 hours.
This came to a head when our efforts to comply with General Data Protection Regulation (GDPR) requirements revealed gaps in our infrastructure that would require us to clean up our data, while simultaneously maintaining operational reliability and reducing data processing times. Something had to change.
In this post, we share how we modernized our data infrastructure by embracing a streaming lakehouse architecture, achieving real-time processing capabilities at a fraction of the cost while reducing operational complexity. With this modernization effort, we reduced analytics data latencies from 18 hours to mere minutes, while also removing the need for using Kafka as a permanent storage for our change log streams.
The problem: Why we needed change
We started this transformation by initiating a migration from self-managed Apache Kafka to Amazon Managed Streaming for Apache Kafka (Amazon MSK), which significantly reduced our operational overhead and enhanced security. Amazon MSK’s express brokers also provided better elasticity for our Apache Kafka clusters. While these improvements were a promising start, we recognized the need for a more fundamental architectural change
Legacy architecture pain points
Let’s examine the specific challenges and limitations of our previous architecture that prompted us to seek a modern solution.
The following diagram depicts Yelp’s original data architecture.
Kafka topics proliferated across our infrastructure, creating long processing chains. As a result, each hop added latency, operational overhead, and storage costs. The system’s reliance on Kafka for both ingestion and storage created a fundamental bottleneck—Kafka’s architecture, optimized for high-throughput messaging, wasn’t designed for long-term storage and to handle complex querying patterns.
Another challenge was our custom “Yelp CDC” format—a proprietary change data capture language—was powerful and tailored to our needs. However, as our team grew and our use cases expanded, it introduced complexity and a steeper learning curve for new engineers. It also made integrations with off-the-shelf systems more complex and maintenance intensive.
The cost and latency trade-off
The traditional trade-off between real-time processing and cost efficiency had us caught in an expensive bind. Real-time streaming systems demand significant resources to maintain state within compute engines like Apache Flink, keep multiple copies of data across Kafka clusters, and run always-on processing jobs. Our infrastructure costs were growing, and it was largely driven by:
Long Kafka chains: Data often traversed 4-5 Kafka topics before reaching its destination and each topic was replicated for reliability
Duplicate data storage: The same data existed in multiple formats across different systems—raw in Kafka, processed in intermediate topics, and final forms in data warehouses and Flink RocksDB for join-like use cases
Complex custom tooling maintenance: The proprietary nature of our tools meant engineering resources were focused on maintenance rather than building new capabilities
Meanwhile, our business requirements became more demanding. Teams at Yelp needed faster insights, near-real-time results, and the ability to quickly run complex historical analyses without delay. This pushed us to shape our new architecture to improve streaming discovery and metadata visibility, provide more flexible transformation tooling, and simplify operational workflows with faster recovery times.
Understanding the streamhouse concept
To understand how we solved our data infrastructure challenges, it’s important to first grasp the concept of a streamhouse and how it differs from traditional architectures.
Evolution of data architecture
To understand why a streaming lakehouse or streamhouse was the answer to our challenges, it’s helpful to trace the evolution of data architectures. The journey from data warehouses to modern streaming systems reveals why each generation solved certain problems while creating new ones.
Data warehouses like Amazon Redshift and Snowflake brought structure and reliability to analytics, but their batch-oriented nature meant accepting hours or days of latency. Data lakes emerged to handle the volume and variety of big data, using low-cost object storage like Amazon S3, but often became “data swamps” without proper governance. The lakehouse architecture, pioneered by technologies like Apache Iceberg and Delta Lake, promised to combine the best of both, the structure of warehouses with the flexibility and economics of lakes.
But even lakehouses were designed with batch processing in mind. While they added streaming capabilities, these were often bolted on rather than fundamental to the architecture. What we needed was something different: a reimagining that treated streaming as a first-class citizen while maintaining lakehouse economics.
What makes a streamhouse different
A streamhouse, as we define it, is “a stream processing framework with a storage layer that leverages a table format, making intermediate streaming data directly queryable.” This seemingly simple definition represents a fundamental shift in how we think about data processing.
Traditional streaming systems maintain dynamic tables like materialized views in databases, but these aren’t directly queryable. You can only consume them as streams, limiting their utility for ad-hoc analysis or debugging. Lakehouses, conversely, excel at queries but struggle with low-latency updates and complex streaming operations like out-of-order event handling or partial updates.
The streamhouse bridges this gap by:
Treating batch as a special case of streaming, rather than a separate paradigm
Making data, including intermediate processing results, queryable via SQL
Providing streaming-native features like database change-data capture (CDC) and temporal joins
Leveraging cost-effective object storage while maintaining minute-level latencies
Core capabilities we needed
Our requirements for a streaming lakehouse were shaped by years of operating at scale:
Real-time processing with minute-level latency: While sub-second latency wasn’t necessary for most use cases, our previous hours-long delays weren’t acceptable. The sweet spot was processing latencies measured in minutes fast enough for real-time decision-making but relaxed enough to leverage cost-effective storage.
Efficient CDC handling: With numerous MySQL databases powering our applications, the ability to efficiently capture and process database changes was crucial. The solution needed to handle both initial snapshots and ongoing changes seamlessly, without manual intervention or downtime.
Cost-effective scaling: The architecture had to break the linear relationship between data volume and cost. This meant leveraging tiered storage, with hot data on fast storage and cold data on low-cost object storage, all while maintaining query performance.
Built-in data management: Schema evolution, data lineage, time travel queries, and data quality controls needed to be first-class features, not afterthoughts. Our experience maintaining our custom Schematizer taught us that these capabilities were essential for operating at scale.
The solution architecture
Our modernized data infrastructure combines several key technologies into a cohesive streamhouse architecture that addresses our core requirements while maintaining operational efficiency.
Our technology stack selection
We carefully selected and integrated several proven technologies to build our streamhouse solution.The following diagram depicts Yelp’s new data architecture.
After extensive evaluation, we assembled a modern streaming lakehouse stack, streamhouse, built on proven open source technologies:
Amazon MSK continues to deliver existing streams as they did before from source applications and services.
Apache Flink on Amazon EKS served as our compute engine, a natural choice given our existing expertise and investment in Flink-based processing. Its powerful stream processing capabilities, exactly-once semantics, and mature framework made it ideal for the computational layer.
Apache Paimon emerged as the key innovation, providing the streaming lakehouse storage layer. Born from the Flink community’s FLIP-188 proposal for built-in dynamic table storage, Paimon was designed from the ground up for streaming workloads. Its LSM-tree-based architecture provided the high-speed ingestion capabilities we needed.
Amazon S3 serves as our streamhouse storage layer, offering highly scalable capacity at a fraction of the cost. The shift from compute-coupled storage (Kafka brokers) to object storage represented a fundamental architectural change that unlocked massive cost savings.
Flink CDC connectors replaced our custom CDC implementations, providing battle-tested integrations with databases like MySQL. These connectors handled the complexity of initial snapshots, incremental updates, and schema changes automatically.
Architectural transformation
The transformation from our legacy architecture to the streamhouse model involved three key architectural shifts:
1. Decoupling ingestion from storage
In our old world, Kafka handled both data ingestion and storage, creating an expensive coupling. Every byte ingested had to be stored on Kafka brokers with replication for reliability. Our new architecture separated these concerns: Flink CDC handled ingestion by immediately writing to Paimon tables backed by S3. This separation reduced our storage costs by over 80% and improved reliability through the 11 nines of durability of S3.
2. Unified data format
The migration from our proprietary CDC format to the industry-standard Debezium format was more than a technical change. It reflected a broader move toward community-supported standards. We built a Data Format Converter that bridged the gap, allowing legacy streams to continue functioning while new streams leveraged standard formats. This approach facilitated backward compatibility while paving the way for future simplification.
3. Streamhouse tables
Perhaps the most radical change was replacing some of our Kafka topics with Paimon tables. These weren’t just storage locations—they were dynamic, versioned, queryable entities that supported:
Time travel queries in the table’s snapshot retention period
Automatic schema evolution without downtime
SQL-based access for both streaming and batch workloads
Built-in compaction and optimization
Key design decisions
Several key design decisions shaped our implementation:
SQL as the primary interface: Rather than requiring developers to write Java or Scala code for every transformation, SQL became our lingua franca. This democratized access to streaming data, allowing analysts and data scientists to work with real-time data using familiar tools.
Separation of compute and storage: By decoupling these layers, we could scale them independently. A spike in processing needs no longer meant provisioning more storage, and historical data could be kept indefinitely without impacting compute costs.
Embracing open source standards: The shift from home-grown formats and tools to community-supported projects reduced our maintenance burden and accelerated feature development. When issues arose, our engineers could leverage community knowledge rather than debugging in isolation.
Implementation journey
Our transition to the new streamhouse architecture followed a carefully planned path, encompassing prototype development, phased migration, and systematic validation of each component.
Migration strategy
Our migration to the streamhouse architecture required careful planning and execution. The strategy had to balance the need for transformation with the reality of maintaining critical production systems.
1. Prototype development
Our journey began with building foundational components:
Pure Java client library: Removing Scala dependencies were crucial for broader adoption. Our new library removed reliance on Yelp-specific configurations, allowing it to run in many environments.
Data Format Converter: This bridge component translated between our proprietary CDC format and the standard Debezium format, making sure existing consumers could continue operating during the migration.
Paimon ingestor: A Flink job that could ingest data from Kafka sources into Paimon tables, handling schema evolution automatically.
2. Phased rollout approach
Rather than attempting a “big bang” migration, we adopted a per-use case approach—moving a vertical slice of data rather than the entire system at once. Our phased rollout followed these steps:
Select a representative, real-world use case that provides broad coverage of the existing feature set.
In our use case, this included data sourced from both databases and event streams, with writes going to Cassandra and Nrtsearch
Re-implement the use case on the new stack in a development environment using sample data to test the logic
Shadow-launch the new stack in production to test it at scale
This was a critical step for us, as we had to iterate through various configuration tweaks before the system could reliably sustain our production traffic.
Verify the new production deployment against the legacy system’s output
Switch live traffic to the new system only after both the Yelp Platform team and data owners are confident in its performance and reliability
Decommission the legacy system for that use case once the migration is complete
This phased approach allowed our team to build confidence, identify issues early, and refine our processes before touching business-critical systems in production.
Technical challenges we overcame
The migration surfaced several technical challenges that required innovative solutions:
System integration: We developed comprehensive monitoring to track end-to-end latencies and built automated alerting to detect any degradation in performance.
Performance tuning: Initial write performance to Paimon tables was suboptimal for our higher-throughput streams. After careful analysis, we identified that Paimon was re-reading manifest files from S3 on every commit. To alleviate this, we enabled Paimon’s sink writer coordinator cache setting, which is disabled by default. This massively reduced the number of S3 calls during commits. We also found that writing parallelism in Paimon is limited by the number of “buckets” within a partition. Selecting the right number of buckets to allow you to scale horizontally, but also not spread your data too thinly is important for balancing write performance against query performance.
Data validation: Validating data consistency between our legacy Yelp CDC streams and the new Debezium-based format presented notable challenges. During the parallel run phase, we implemented comprehensive validation frameworks to make sure the Data Format Convertor accurately transformed messages, while maintaining data integrity, ordering guarantees, and schema compatibility across both systems.
Data migration complexity: For consistency, we developed custom tooling to verify ordering guarantees and implemented parallel running of old and new systems. We chose Spark as the framework to implement our validations as every data source and sink in our framework has mature connectors, and Spark is a well-supported system at Yelp.
Simplified streaming stack: By replacing multiple custom components with standardized tools, we avoided years of technical debt in one migration. We reduced our complexity and thereby simplified our entire streaming architecture, leading to higher reliability and less maintenance overhead. Our Schematizer, encryption layer, and custom CDC format were all replaced by built-in features from Paimon and standard Kafka, along with IAM controls across S3 and MSK.
Fine-grained access management: Moving our analytical use cases read via Iceberg unlocked a huge win for us: the ability to enable AWS Lake Formation on our data lake. Previously, our access management relied on large, complex S3 bucket policy documents that were approaching their size limits. By moving to Lake Formation we could build an access request lifecycle into our in-house Access Hub to automate access granting and revocation.
Built-in data management features: Capabilities that would have required months of custom development came out-of-the-box, such as automatic schema evolution, time travel queries, and incremental snapshots for efficient processing.
Potential for reduced operational costs: We anticipate that transitioning from Kafka storage to S3 in a streamhouse architecture will significantly reduce storage costs. Avoiding long Kafka chains will also simplify data pipelines and reduce compute costs.
Enhanced troubleshooting capabilities: The streamhouse architecture promises built-in observability features that will make debugging easier. Rather than having to manually look through event streams for problematic data, which can be time-consuming and complex for multi-stream pipelines, engineers can now query live data directly from tables using standard SQL.
Lessons learned and best practices
Throughout this transformation, we gained valuable insights about both technical implementation and organizational change management that can benefit others undertaking similar modernization efforts.
Technical insights
Our journey revealed several crucial technical lessons:
Battle-tested open source wins: Choosing Apache Paimon and Flink CDC over custom solutions proved wise. The community support, continuous improvements, and shared knowledge base accelerated our development and reduced risk.
SQL interfaces democratize access: Making streaming data accessible via SQL transformed who could work with real-time data. Engineers and analysts familiar with SQL can now understand how streaming pipelines work. The barrier to entry has been significantly lowered as engineers no longer need to understand Flink-specific APIs to create a streaming application.
Separation of storage and compute is fundamental: This architectural principle unlocked cost savings and operational flexibility that wouldn’t have been possible otherwise. Our teams can now optimize storage and compute independently based on their specific needs.
Organizational learnings
The human side of the transformation was equally important:
Phased migration reduces risk: Our gradual approach allowed teams to build confidence and expertise, while maintaining business continuity. Each successful phase created momentum for the next. Building trust with newer systems helps gain velocity in later stages of migrations.
Backward compatibility enables progress: By maintaining compatibility layers, our teams could migrate at their own pace without forcing synchronized changes across the organization.
Investment in learning pays dividends: Giving our teams space to learn new technologies like Paimon and streaming SQL had some opportunity cost, but they paid off through increased productivity and reduced operational burden.
Conclusion
Our transformation to a streaming lakehouse architecture (streamhouse) has revolutionized Yelp’s data infrastructure, delivering impressive results across multiple dimensions. By implementing Apache Paimon with AWS services like Amazon S3 and Amazon MSK, we reduced our analytics data latencies from 18 hours to just minutes while cutting storage costs by 80%. The migration also simplified our architecture by replacing multiple custom components with standardized tools, significantly reducing maintenance overhead and improving reliability.
Key achievements include the successful implementation of real-time processing capabilities, streamlined CDC handling, and enhanced data management features like automatic schema evolution and time travel queries. The shift to SQL-based interfaces has democratized access to streaming data, while the separation of compute and storage has given us unprecedented flexibility in resource optimization. These improvements have transformed not just our technology stack, but also how our teams work with data.
For organizations facing similar challenges with data processing latency, operational costs, and infrastructure complexity, we encourage you to explore the streamhouse approach. Start by evaluating your current architecture against modern streaming solutions, particularly those leveraging cloud services and open-source technologies like Apache Paimon. Make sure to leverage security best practices when implementing your solution. You can find AWS security best practices here. Visit the Apache Paimon website or AWS documentation to learn more about implementing these solutions in your environment.
Effective today, all new Amazon Managed Streaming for Apache Kafka (Amazon MSK) Provisioned clusters with Express brokers will support Intelligent Rebalancing at no additional cost. With this new capability you can perform automatic partition balancing operations when scaling Apache Kafka clusters up or down. Intelligent Rebalancing maximizes the capacity utilization of Amazon MSK clusters with Express brokers by optimally rebalancing Kafka resources on them for better performance, eliminating the need to manage partitions independently or by using third-party tools. Intelligent Rebalancing on Amazon MSK Express brokers performs these operations up to 180 times faster compared to Standard brokers.
We launched Amazon MSK Express brokers in November 2024 to reimagine Apache Kafka for ease of use, best-in-class price performance, and predictable availability. Amazon MSK Express brokers are designed to deliver up to three times more throughput per-broker, scale up to 20 times faster, and reduce recovery time by 90 percent as compared to Standard brokers running Apache Kafka. Since launch, we have expanded Amazon MSK Express brokers to additional AWS Regions, instance types, and most recently increased support to 5x more partitions per Express broker, improving price-performance by up to 50% for partition-bound workloads.
With Intelligent Rebalancing, Amazon MSK Express broker clusters are continuously monitored for resource imbalance or overload based on intelligent Amazon MSK defaults to maximize cluster performance. When required, brokers are efficiently scaled, without affecting cluster availability for clients to produce and consume data. Customers can now take full advantage of the scaling and performance benefits of Amazon MSK Provisioned clusters for Express brokers while simplifying cluster management operations.
In this post we’ll introduce the Intelligent Rebalancing feature and show an example of how it works to improve operation performance.
When to use Intelligent Rebalancing
With Intelligent Rebalancing, Amazon MSK Express brokers now offer a fully automated solution for managing and scaling Kafka clusters, requiring no additional tools or configuration. Intelligent Rebalancing is enabled by default on all new Amazon MSK Express brokers clusters, so we recommend always keeping it on. Intelligent Rebalancing uses Amazon MSK best practices to trigger automatic rebalancing during the following situations:
Scaling in and out clusters: When customers add or remove brokers from their Amazon MSK Express brokers clusters, Intelligent Rebalancing automatically redistributes partitions to balance resource utilization across the brokers. This ensures that the cluster continues to operate at peak performance, making scaling in and out possible with a single update operation.
Steady-state rebalancing: Even during normal operations, Intelligent Rebalancing continuously monitors the Amazon MSK Express brokers cluster and triggers rebalancing when it detects resource imbalances or hotspots. For example, if certain brokers become overloaded due to uneven distribution of partitions or skewed traffic patterns, Intelligent Rebalancing will automatically move partitions to less utilized brokers to restore balance.
How to use Intelligent Rebalancing
To demonstrate the power of Intelligent Rebalancing, let’s run a few tests on an Amazon MSK Express brokers cluster:
Scaling test: We’ll start by creating an Amazon MSK Express brokers cluster with 3 brokers. We’ll then rapidly scale the cluster up to 6 brokers and back down to 3 brokers, simulating a sudden spike in workload. With Intelligent Rebalancing enabled, you’ll see that the rebalancing of partitions is completed within 5-10 minutes, so that the cluster can sustain the increased throughput without any drop in performance.
You can track the current and historical rebalancing operations using the metric RebalanceInProgress. In the picture below, you can also see that the clients on the producer side are not impacted during this rebalancing.
Next, we’ll create an imbalance in the cluster by directing a large portion of the traffic to a single broker. You’ll see that Intelligent Rebalancing detects this imbalance within minutes and automatically redistributes the partitions, restoring the cluster to an optimal state.
The intelligent rebalancing feature detects hotspots and automatically redistributes affected partitions across other brokers to optimize resource utilization. Without Intelligent Rebalancing, the resource imbalance would persist, potentially leading to performance issues or the need for manual intervention by the customer.
These tests showcase how Intelligent Rebalancing with Amazon MSK Express brokers enables scaling Kafka clusters seamlessly while maintaining consistently high performance, even under varying workload conditions.
Conclusion
Intelligent Rebalancing for Amazon MSK Provisioned clusters with Express brokers are currently being rolled out over the next few weeks in all AWS Regions where Amazon MSK Express brokers are supported. This feature is automatically enabled for all new Amazon MSK Provisioned clusters with Express brokers at no additional cost.
Although event source mappings (ESM) offer a powerful mechanism for integrating AWS Lambda with stream and queue-based sources, configuring them to align with high-level architectural goals can sometimes involve navigating a broad set of options and parameters. Achieving an optimal configuration typically requires mapping developer intent to several technical settings, which can introduce inefficiencies or operational overhead.
In May 2025, AWS launched the AWS Serverless MCP Server, which provided AI-powered assistance for serverless application development, including infrastructure provisioning, deployment automation, and architectural guidance. Building on this foundation, AWS is now expanding the Serverless MCP Server to include specialized ESM tools.
These new dedicated tools in the AWS Serverless Model Context Protocol (MCP) Server combine the power of AI assistance with ESM expertise to enhance how developers build and manage event-driven serverless applications using Lambda. The new ESM tools provide contextual guidance specific to ESM configuration that address the challenges of event-driven development.
This post describes how the new tools under Serverless MCP Server work with AI coding assistants to streamline event source mapping management. Learn how to use this solution to accelerate your event-driven development workflow and build robust, high-performing applications more efficiently.
Overview
An event source mapping is a Lambda resource that reads items from stream and queue-based services and invokes a function with batches of records. Within an event source mapping, resources called event pollers actively poll for new messages and invoke functions. Using ESMs, AWS Lambda functions can automatically consume events from various sources without requiring custom polling infrastructure. Lambda handles the complexity of scaling, batching, filtering, and error handling, helping developers focus on business logic.
Navigating ESM configurations
Configuring these mappings optimally, especially for virtual private cloud (VPC)-based sources like Apache Kafka, requires additional understanding of networking, permissions, and performance tuning.
When working with event source mappings, developers need to address several technical considerations. For Kafka Streams using VPC-based Amazon Managed Streaming for Apache Kafka or self-managed Apache Kafka, configurations involve networking setup to enable Lambda access to Kafka topics. Developers must manage bootstrap servers, AWS Identity and Access Management (IAM) permissions, and topic access settings, while also handling authentication including SASL/SCRAM credentials, mTLS certificate management, and Kafka ACL permissions.
Developers need to know how to translate performance requirements, such as processing 1,000 events per second, into specific ESM parameter configurations. Depending on the stream source, this involves determining appropriate batch sizes, parallelization factors, and retry policies while managing iterator age, offset lag and potential timeout issues. Additionally, developers need visibility into configuration effectiveness and other diagnostic information to optimize resource allocation and ensure reliable event processing.
Dedicated event source mapping tools
The new ESM tools in the open source AWS Serverless MCP Server address these challenges by providing AI assistants with proven knowledge of event source mapping patterns and best practices. These tools guide developers through the entire ESM lifecycle, from initial setup to optimization and troubleshooting. They also enhance the event-driven development experience by translating the developers intent into detailed, technical configuration, helping developers express high-level goals such as desired throughput, latency, or reliability requirements. The new tools cover all areas of event source mapping management:
Setup and configuration: Developers initialize new event source mapping configurations using AWS Serverless Application Model (AWS SAM) templates, select appropriate event source settings, and configure networking requirements for VPC-based sources like Amazon MSK.
Optimization and tuning: As applications evolve, the tools assists with fine-tuning ESM parameters like batch size, batching window, retry policies, and parallelization factors based on performance goals and telemetry data.
Troubleshooting and diagnostics: Specialized tools diagnose ESM connectivity issues, analyze Amazon CloudWatch Logs and metrics, and recommend solutions for common problems like VPC misconfigurations or permission errors.
Event source mapping tools in action
This example walks you through a scenario of creating, optimizing, and troubleshooting an event source mapping for Amazon MSK to demonstrate the capabilities of the new ESM tools.
Prerequisites and installation
To get started, download or update the AWS Serverless MCP Server from GitHub or Python Package Index (PyPi) and follow the installation instructions. You can use this MCP server with any AI coding assistant of your choice, such as Amazon Q Developer, Cursor, Cline, Kiro, and more.
Add the following code to your MCP client configuration:
The Serverless MCP Server incorporates built-in guardrails to ensure secure and controlled development. By default, the server operates in a read-only mode, allowing only non-mutating actions. With this safety-first approach, you can explore ESM capabilities and architectural patterns while preventing unintended changes to your applications or infrastructure.
Creating and configuring an event source mapping
Imagine you want to set up a Lambda function to process events from an Amazon MSK cluster. Start by prompting your AI assistant:
Create a new Kafka cluster and a VPC named <your-vpc-name> in <your-aws-region>. The cluster should be in the VPC’s private subnets. Then, create a Lambda function to consume from the stream within the same VPC cluster. Prefix all created resources with <your-prefix>.
The agent uses the esm_guidance to receive tailored guidance based on your use case and performance requirements. The tool analyzes your intent and provides step-by-step instructions for setting up the ESM with optimal configurations.
Apart from creating deployment and initialization scripts and supporting documentation, properly configured IAM polices and security groups rules to access the cluster are also generated. The assistant then validates the ESM parameters against AWS limits and best practices.
Next, you want to understand the networking requirements:
My Kafka cluster is in a VPC. What networking configuration do I need for Lambda to access it?
The Serverless MCP Server provides specialized guidance for VPC-based Kafka configurations using the esm_guidance tool with guidance_type=”networking”. This guidance provides detailed information about subnet requirements, security group rules, and NAT gateway setup, and it validates your network topology for reliable connectivity.
Optimizing event source mapping performance
After your ESM is running, you notice that processing latency is higher than expected. You can ask for optimization guidance:
I have an ESM with UUID <your-esm-uuid> in <your-aws-region>. My target throughput is between 10 MB/s and 100 MB/s. Please update my ESM configuration to meet these throughput requirements while optimizing the cost of the event pollers.
The server uses the esm_optimize tool to analyze your current configuration and provide optimization recommendations. The tool supports three main actions:
Analysis mode: (action="analyze") Analyzes configuration tradeoffs for your optimization targets (throughput, latency, cost, failure rate)
Validation mode: (action="validate") Validates your ESM configuration against AWS limits and event source restrictions
Template generation: (action="generate_template") Creates updated AWS SAM templates with optimized configurations
You can use this tool to get guidance on your event source mapping configurations for Amazon SQS, Amazon Kinesis Data Streams, and Amazon DynamoDB Streams. Here are two examples:
I have a Kinesis stream with 100 shards receiving 100 MB/s of data. My Lambda function processes each record in about 50ms. Currently, my ESM has ParallelizationFactor=1 and BatchSize=100, but I’m seeing high iterator age (over 60 seconds) during peak times. How should I optimize my ESM configuration to reduce processing latency and handle the throughput?
I have an SQS standard queue that receives 50,000 messages per hour during peak times. Each message takes about 2 seconds to process. My current ESM configuration has BatchSize=10 and no ScalingConfig set. I’m seeing message delays during peak hours. How should I optimize my ESM configuration for better throughput while keeping costs reasonable?
The tool generates updated AWS Serverless Application Model (AWS SAM) templates with the recommended configurations, making it easy to apply the changes through your deployment pipeline. However, it always requires explicit user confirmation before any deployment.
Troubleshooting event source mapping issues
When an issue arises, the ESM tools provide diagnostic capabilities. For example, if your ESM stops processing events:
I have a cluster called <your-kafka-cluster-name> and a consumer Lambda function named <your-lambda-function-name>in <your-aws-region>. Please investigate why my ESM (UUID: <your-esm-uuid>) trigger is not working and provide updated configurations to resolve the issue.
The server uses the esm_kafka_troubleshoot tool to provide comprehensive troubleshooting for Apache Kafka clusters. The tool supports two main modes:
Diagnostic mode: (issue_type="diagnosis") Analyzes your ESM status and provides diagnostic indicators. This helps identify whether timeouts occur before or after reaching Kafka brokers. It categorizes issues into specific types for targeted resolution.
Resolution mode: Provides step-by-step resolution guidance for specific issues.
The tool automatically detects your event source type and provides tailored guidance. It validates VPC connectivity, examines IAM permissions, checks security group configurations, and analyzes CloudWatch Logs to provide a detailed diagnosis report with specific remediation steps.
Key benefits
The event source mapping tools in the AWS Serverless MCP Server provide unique advantages over traditional event source mapping configuration approaches:
AI-powered configuration translation: The tools translate high-level developer intent (such as process 1,000 events per second) into specific ESM parameters like batch size, parallelization factor, and batching window.
Complete infrastructure-as-code generation: Unlike generic AWS CLI tools that provide individual commands, ESM tools generate complete AWS SAM templates, initialization scripts, cleanup scripts, and validation scripts for end-to-end automation.
Proactive network validation: For VPC-based event sources like Amazon MSK or self-managed Kafka, the tools validate network topology, security group rules, and connectivity before deployment, preventing common silent failures.
Context-aware troubleshooting: The diagnostic tools correlate ESM status, CloudWatch metrics, VPC configuration, and IAM permissions to provide comprehensive root cause analysis with specific remediation steps.
New tools available in the Serverless MCP Server
The event source mapping tools are designed to minimize trust permission prompts by using a small set of primary tools that internally call specialized functions. The tools can be classified into three main categories:
esm_guidance: This tool provides comprehensive guidance on creating and configuring event source mappings for all event sources (DynamoDB, Kinesis, Kafka, SQS). It handles setup, networking guidance, and troubleshooting based on the guidance_type parameter. The tool automatically generates AWS SAM templates, IAM policies, and security group configurations.
esm_optimize: This advanced optimization tool analyzes configuration tradeoffs, validates ESM settings, and generates AWS SAM templates for performance tuning. It supports three actions:
analyze: Provides configuration tradeoff analysis for failure rate, latency, throughput, and cost optimization
validate: Validates ESM configurations against AWS limits and event source restrictions
generate_template: Creates AWS SAM templates with optimized configurations
esm_kafka_troubleshoot: This specialized troubleshooting tool for Kafka ESM issues supports both Amazon MSK and self-managed Apache Kafka clusters. It also provides diagnostic capabilities and step-by-step resolution guidance for connectivity, authentication, and network issues.
The primary tools internally call specialized helper functions to provide comprehensive functionality that help generate IAM polices, security groups, scaling and concurrency configurations, and validate configurations.
Visit the Serverless MCP Server documentation for the full list of tools and resources.
Best practices and considerations
When building event-driven applications with the AWS Serverless MCP Server, start by using its guidance tools for architectural decisions. The server helps you choose appropriate event sources, understand networking requirements, and configure optimal settings based on your performance goals.For Kafka-based ESMs, pay special attention to VPC configuration. Use the server’s network troubleshooting tools to validate connectivity before deployment. The server can detect common issues like missing NAT gateways, incorrect security group rules, or subnet routing problems.Monitor your event source mappings continuously using the server’s diagnostic tools. Set up alerts for key metrics like iterator age, error rates, and throttling. The server can help you interpret these metrics and recommend configuration adjustments to maintain optimal performance.
Conclusion
The new event source mapping tools in the open-source AWS Serverless MCP Server simplify event source mapping management throughout the development lifecycle, from initial setup to ongoing optimization and troubleshooting. By combining AI assistance with ESM expertise, it helps developers build and deploy event-driven applications more efficiently while avoiding common configuration pitfalls.
As organizations continue to adopt event-driven serverless computing, tools that simplify ESM management and accelerate delivery become increasingly valuable.
To get started, visit the GitHub repository and explore the documentation. Share your experiences and suggestions through the GitHub repository to improve the MCP server’s capabilities and help shape the future of AI-assisted event-driven development.
For more serverless learning resources, visit Serverless Land.
Efficient real-time synchronization of data within data lakes present challenges. Any data inaccuracies or latency issues can significantly compromise analytical insights and subsequent business strategies. Organizations increasingly require synchronized data in near real-time to extract actionable intelligence and respond promptly to evolving market dynamics. Additionally, scalability remains a concern for data lake implementations, which must accommodate expanding volumes of streaming data and maintain optimal performance without incurring high operational costs.
Schema evolution is the process of modifying the structure (schema) of a data table to accommodate changes in the data over time, such as adding or removing columns, without disrupting ongoing operations or requiring a complete data rewrite. Schema evolution is vital in streaming data environments for several reasons. Unlike batch processing, streaming pipelines operate continuously, ingesting data in real time from sources that are actively serving production applications. Source systems naturally evolve over time as businesses add new features, refine data models, or respond to changing requirements. Without proper schema evolution capabilities, even minor changes to source schemas can force streaming pipeline shutdowns, requiring developers to manually reconcile schema differences and rebuild tables.
Such disruptions reduce the core value proposition of streaming architectures—continuous, low-latency data processing. Organizations can maintain uninterrupted data flows and keep source systems evolving independently by using the seamless schema evolution provided by Apache Iceberg. This reduces operational friction and maintains the availability of real-time analytics and applications even as underlying data structures change.
Apache Iceberg is an open table format, delivering essential capabilities for streaming workloads, including robust schema evolution support. This critical feature enables table schemas to adapt dynamically as source database structures evolve, maintaining operational continuity. Consequently, when database columns undergo additions, removals, or modifications, the data lake accommodates these changes seamlessly without requiring manual intervention or risking data inconsistencies.
Our comprehensive solution showcases an end-to-end real-time CDC pipeline that enables immediate processing of data modifications from Amazon Relational Database Service (Amazon RDS) for MySQL, streaming altered records directly to AWS Glue streaming jobs using Amazon Managed Streaming for Apache Kafka (Amazon MSK) Serverless. These jobs continually process incoming changes and update Iceberg tables on Amazon Simple Storage Service (Amazon S3) so that the data lake reflects the current state of the operational database environment in real time. By using Apache Iceberg’s comprehensive schema evolution support, our ETL pipeline automatically adapts to database schema modifications, providing data lake consistency and currentness without manual intervention. This approach combines complete process control with instantaneous analytics on operational data, eliminating traditional latency, and future-proofs the solution to address evolving organizational data needs. The architecture’s inherent flexibility facilitates adaptation to diverse use cases requiring immediate data insights.
Solution overview
To effectively address streaming challenges, we propose an architecture using Amazon MSK Serverless, a comprehensive managed Apache Kafka service that autonomously provisions and scales computational and storage resources. This solution offers a frictionless mechanism for ingesting and processing streaming data without the complexity of capacity management. Our implementation uses Amazon MSK Connect with the Debezium MySQL connector to capture and stream database modifications in real time. Rather than employing traditional batch processing methodologies, we implement an AWS Glue streaming job that directly consumes data from Kafka topics, processes CDC events as they occur, and writes transformed data to Apache Iceberg tables on Amazon S3.
The workflow consists of the following:
Data flows from Amazon RDS through Amazon MSK Connect using the Debezium MySQL connector to Amazon MSK Serverless. This represents a CDC pipeline that captures database changes from the relational database and streams them to Kafka.
From Amazon MSK Serverless, the data then moves to AWS Glue job, which processes the data and stores it in Amazon S3 as Iceberg tables. The AWS Glue job interacts with the AWS Glue Data Catalog to maintain metadata about the datasets.
Analyze the data using the serverless interactive query service Amazon Athena, which can be used to query the iceberg table created in Data Catalog. This allows for interactive data analysis without managing infrastructure.
The following diagram illustrates the architecture that we implement through this post. Each number corresponds to the preceding list and shows major components that you implement.
Prerequisites
Before getting started, make sure you have the following:
An active AWS account with billing enabled
An AWS Identity and Access Management (IAM) user with specific permissions to create and manage resources, such as a virtual private cloud (VPC), subnet, security group, IAM roles, NAT gateway, internet gateway, Amazon Elastic Compute Cloud (Amazon EC2) client, MSK Serverless, MSK Connector and its plugin AWS Glue job, and S3 buckets.
Sufficient VPC capacity in your chosen AWS Region.
For this post, we create the solution resources in the US East (N. Virginia) – us-east-1 Region using AWS CloudFormation templates. In the following sections, we show you how to configure your resources and implement the solution.
Configuring CDC and processing using AWS CloudFormation
In this post, you use the CloudFormation template vpc-msk-mskconnect-rds-client-gluejob.yaml. This template sets up the streaming CDC pipeline resources such as a VPC, subnet, security group, IAM roles, NAT, internet gateway, EC2 client, MSK Serverless, MSK Connect, Amazon RDS, S3 buckets, and AWS Glue job.
To create the solution resources for the CDC pipeline, complete the following steps:
Launch the stack vpc-msk-mskconnect-rds-client-gluejob.yaml using the CloudFormation template:
Provide the parameter values as listed in the following table.
A
B
C
1
Parameters
Description
Sample value
2
EnvironmentName
An environment name that is prefixed to resource names.
msk-iceberg-cdc-pipeline
3
DatabasePassword
Database admin account password.
****
4
InstanceType
MSK client EC2 instance type.
t2.micro
5
LatestAmiId
Latest AMI ID of Amazon Linux 3 for ec2 instance. You can use the default value.
IP range (CIDR notation) for the public subnet in the first Availability Zone.
10.192.10.0/24
8
PublicSubnet2CIDR
IP range (CIDR notation) for the public subnet in the second Availability Zone.
10.192.11.0/24
9
PrivateSubnet1CIDR
IP range (CIDR notation) for the private subnet in the first Availability Zone.
10.192.20.0/24
10
PrivateSubnet2CIDR
IP range (CIDR notation) for the private subnet in the second Availability Zone.
10.192.21.0/24
11
NumberOfWorkers
Number of workers for AWS Glue streaming job.
3
12
GlueWorkerType
Worker type for AWS Glue streaming job. For example, G.1X.
G.1X
13
GlueDatabaseName
Name of the AWS Glue Data Catalog database.
glue_cdc_blogdb
14
GlueTableName
Name of the AWS Glue Data Catalog table.
iceberg_cdc_tbl
The stack creation process can take approximately 25 minutes to complete. You can check the Outputs tab for the stack after the stack is created, as shown in the following screenshot.
Following the successful deployment of the CloudFormation stack, you now have a fully operational Amazon RDS database environment. The database instance contains the salesdb database with the customer table populated with 30 data records.
These records have been streamed to the Kafka topic through the Debezium MySQL connector implementation, establishing a reliable CDC pipeline. With this foundation in place, proceed to the next phase of the data architecture: near real-time data processing using the AWS Glue streaming job.
Run the AWS Glue streaming job
To transfer the data load from the Kafka topic (created by the Debezium MySQL connector for database table customer) to the Iceberg table, run the AWS Glue streaming job configured by the CloudFormation setup. This process will migrate all existing customer data from the source database table to the Iceberg table. Complete the following steps:
On the CloudFormation console, choose the stack vpc-msk-mskconnect-rds-client-gluejob.yaml
On the Outputs tab, retrieve the name of the AWS Glue streaming job from the GlueJobName row. In the following screenshot, the name is IcebergCDC-msk-iceberg-cdc-pipeline.
On the AWS Glue console, choose ETL jobs in the navigation pane.
Search for the AWS Glue job named IcebergCDC-msk-iceberg-cdc-pipeline.
Choose the job name to open its details page.
Choose Run to start the job. On the Runs tab, confirm if the job ran without failure.
You need to wait approximately 2 minutes for the job to process before continuing. This pause allows the jobrun to fully process records from the Kafka topic (initial load) and create the Iceberg table.
Query the Iceberg table using Athena
After the AWS Glue streaming job has successfully started and the Iceberg table has been created in the Data Catalog, follow these steps to validate the data using Athena:
On the Athena console, navigate to the query editor.
Choose the Data Catalog as the data source.
Choose the database glue_cdc_blogdb.
To validate the data, enter the following query to preview the data and find the total count:
SELECT id, name, mktsegment FROM "glue_cdc_blogdb"."iceberg_cdc_tbl" order by id desc limit 40;

SELECT count(*) as total_rows FROM "glue_cdc_blogdb"."iceberg_cdc_tbl";
The following screenshot shows the output of the example query.
After performing the preceding steps, you’ve established a complete near real-time data processing pipeline by running an AWS Glue streaming job that transfers data from Kafka topics to an Apache Iceberg table, then verified the successful data migration by querying the results through Amazon Athena.
Upload incremental (CDC) data for further processing
Now that you’ve successfully completed the initial full data load, it’s time to focus on the dynamic aspects of the data pipeline. In this section, we explore how the system handles ongoing data modifications such as insertions, updates, and deletions in Amazon RDS for MySQL database. These changes won’t go unnoticed. Our Debezium MySQL connector stands ready to capture each modification event, transforming database changes into a continuous stream of data. Working in tandem with our AWS Glue streaming job, this architecture is designed to promptly process and propagate every change in our source database through our data pipeline.Let’s see this real-time data synchronization mechanism in action, demonstrating how our modern data infrastructure maintains consistency across systems with minimal latency. Follow these steps:
On the Amazon EC2 console, access the EC2 instance that you created using the CloudFormation template named as KafkaClientInstance.
Log in to the EC2 instance using AWS Systems Manager Agent (SSM Agent). Select the instance named as KafkaClientInstance and then choose Connect.
Enter the following commands to insert the data into the RDS table. Use the same database password you entered when you created the CloudFormation stack.
Now perform the insert, update, and delete in the CUSTOMER table.
use salesdb;

INSERT INTO customer VALUES(31, 'Customer Name 31', 'Market segment 31');
INSERT INTO customer VALUES(32, 'Customer Name 32', 'Market segment 32');

UPDATE customer SET name='Customer Name update 29', mktsegment='Market segment update 29' WHERE id = 29;
UPDATE customer SET name='Customer Name update 30', mktsegment='Market segment update 30' WHERE id = 30;

DELETE FROM customer WHERE id = 27;
DELETE FROM customer WHERE id = 28;
Validate the data to verify the insert, update, and delete records in the Iceberg table from Athena, as shown in the following screenshot.
After performing the preceding steps, you’ve learned how our CDC pipeline handles ongoing data modifications by performing insertions, updates, and deletions in the MySQL database and verifying how these changes are automatically captured by Debezium MySQL connector, streamed through Kafka, and reflected in the Iceberg table in near real time.
Schema evolution: Adding new columns to the Iceberg table
The schema evolution mechanism in this implementation provides an automated approach to detecting and adding new columns from incoming data to existing Iceberg tables. Although Iceberg inherently supports robust schema evolution capabilities (including adding, dropping, and renaming columns, updating types, and reordering), this code specifically automates the column addition process for streaming environments. This automation uses Iceberg’s underlying schema evolution capabilities, which guarantee correctness through unique column IDs that ensure new columns never read existing values from another column. By handling column additions programmatically, the system reduces operational overhead in streaming pipelines where manual schema management would create bottlenecks. However, dropping and renaming columns, updating types, and reordering still required manual intervention.
When new data arrives through Kafka streams, the handle_schema_evolution() function orchestrates a four-step process to ensure seamless table schema updates.
It analyzes the incoming batch DataFrame to infer its schema structure, cataloging all column names and their corresponding data types.
It retrieves the existing Iceberg table’s schema from the AWS Glue catalog to establish a baseline for comparison.
The system then performs a schema comparison using method compare_schemas() between batch schema with existing table schema.
If the incoming frame contains fewer columns than the catalog table, no action is taken.
It identifies any new columns present in the incoming data that don’t exist in the current table structure and returns a list of new columns that need to be added.
New columns will be added at the last.
Handle type evolution isn’t supported. If needed, you can handle the same at comment # Handle type evolution in the compare_schemas() method.
If the destination table has columns that are dropped in the source table, it doesn’t drop those columns. If that is required for your use case, you can use drop column manually usingALTER TABLE ... DROP COLUMN.
Renaming the column isn’t supported. To rename the column use case, manually evolve the schema using ALTER TABLE … RENAME COLUMN.
Finally, if new columns are discovered, the function executes ALTER TABLE … ADD COLUMN statements to evolve the Iceberg table schema, adding the new columns with their appropriate data types.
This approach eliminates the need for manual schema management and prevents data pipeline failures that would typically occur when encountering unexpected fields in streaming data. The implementation also includes proper error handling and logging to track schema evolution events, making it particularly valuable for environments where data structures frequently change.
def infer_schema_from_batch(batch_df):
    """
    Infer schema from the batch DataFrame
    Returns a dictionary with column names and their inferred types
    """
    schema_dict = {}
    for field in batch_df.schema.fields:
        schema_dict[field.name] = field.dataType
    return schema_dict

def get_existing_table_schema(spark, table_identifier):
    """
    Read the existing table schema from the Iceberg table
    Returns a dictionary with column names and their types
    """
    try:
        existing_df = spark.table(table_identifier)
        schema_dict = {}
        for field in existing_df.schema.fields:
            schema_dict[field.name] = field.dataType
        return schema_dict
    except Exception as e:
        print(f"Error reading existing table schema: {e}")
        return {}

def compare_schemas(batch_schema, existing_schema):
    """
    Compare batch schema with existing table schema
    Returns a list of new columns that need to be added
    """
    new_columns = []

    for col_name, col_type in batch_schema.items():
        if col_name not in existing_schema:
            new_columns.append((col_name, col_type))
        elif existing_schema[col_name] != col_type:
            # Handle type evolution if needed
            print(f"Warning: Column {col_name} type mismatch - existing: {existing_schema[col_name]}, new: {col_type}")

    return new_columns

def spark_type_to_sql_string(spark_type):
    """
    Convert Spark DataType to SQL string representation for ALTER TABLE
    """
    type_mapping = {
        'IntegerType': 'INT',
        'LongType': 'BIGINT',
        'StringType': 'STRING',
        'BooleanType': 'BOOLEAN',
        'DoubleType': 'DOUBLE',
        'FloatType': 'FLOAT',
        'TimestampType': 'TIMESTAMP',
        'DateType': 'DATE'
    }

    type_name = type(spark_type).__name__
    return type_mapping.get(type_name, 'STRING')

def evolve_table_schema(spark, table_identifier, new_columns):
    """
    Alter the Iceberg table to add new columns
    """
    if not new_columns:
        return

    try:
        for col_name, col_type in new_columns:
            sql_type = spark_type_to_sql_string(col_type)
            alter_sql = f"ALTER TABLE {table_identifier} ADD COLUMN {col_name} {sql_type}"
            print(f"Executing schema evolution: {alter_sql}")
            spark.sql(alter_sql)
            print(f"Successfully added column {col_name} with type {sql_type}")
    except Exception as e:
        print(f"Error during schema evolution: {e}")
        raise e

def handle_schema_evolution(spark, batch_df, table_identifier):
    """
    schema evolution steps
    1. Infer schema from batch DataFrame
    2. Read existing table schema
    3. Compare schemas and identify new columns
    4. Alter table if schema evolved
    """
    # Step 1: Infer schema from batch DataFrame
    batch_schema = infer_schema_from_batch(batch_df)
    print(f"Batch schema: {batch_schema}")

    # Step 2: Read existing table schema
    existing_schema = get_existing_table_schema(spark, table_identifier)
    print(f"Existing table schema: {existing_schema}")

    # Step 3: Compare schemas
    new_columns = compare_schemas(batch_schema, existing_schema)

    # Step 4: Evolve schema if needed
    if new_columns:
        print(f"Schema evolution detected. New columns: {new_columns}")
        evolve_table_schema(spark, table_identifier, new_columns)
        return True
    else:
        print("No schema evolution needed")
        return False
In this section, we demonstrate how our system handles structural changes to the underlying data model by adding a new status column to the customer table and populating it with default values. Our architecture is designed to seamlessly propagate these schema modifications throughout the pipeline so that downstream analytics and processing capabilities remain uninterrupted while accommodating the enhanced data model. This flexibility is essential for maintaining a responsive, business-aligned data infrastructure that can evolve alongside changing organizational needs.
Add a new status column to the customer table and populate it with default values as Green.
use salesdb;

ALTER TABLE customer ADD COLUMN status VARCHAR(20) NOT NULL;

UPDATE customer SET status = 'Green';
Use the Athena console to validate the data and schema evolution, as shown in the following screenshot.
When schema evolution occurs in an Iceberg table, the metadata.json file undergoes specific updates to track and manage these changes. In job when schema evolution detected, it ran the following query to evolve the schema for the Iceberg table.
ALTER TABLE glue_catalog.glue_cdc_blogdb.iceberg_cdc_tbl ADD COLUMN status string
We checked the metadata.json file in Amazon S3 for iceberg table location, and the following screenshot shows how the schema evolved.
We now explain how our implementation handles schema evolution by automatically detecting and adding new columns from incoming data streams to existing Iceberg tables. The system employs a four-step process that analyzes incoming data schemas, compares them with existing table structures, identifies new columns, and executes the necessary ALTER TABLE statements to evolve the schema without manual intervention, though certain schema changes still require manual handling.
Clean up
To clean up your resources, complete the following steps:
Stop the running AWS Glue streaming job:
On the AWS Glue console, choose ETL jobs in the navigation pane.
Search for the AWS Glue job named IcebergCDC-msk-iceberg-cdc-pipeline.
Choose the job name to open its details page.
On the Runs tab, select running jobrun and choose Stop job run. Confirm that the job stopped successfully.
Remove the AWS Glue database and table:
On the AWS Glue console, choose Tables in the navigation pane, select iceberg_cdc_tbl, and choose Delete.
Choose Databases in the navigation pane, select glue_cdc_blogdb, and choose Delete.
Delete the CloudFormation stack vpc-msk-mskconnect-rds-client-gluejob.yaml.
Conclusion
This post showcases a solution that businesses can use to access real-time data insights without the traditional delays between data creation and analysis. By combining Amazon MSK Serverless, Debezium MySQL connector, AWS Glue streaming, and Apache Iceberg tables, the architecture captures database changes instantly and makes them immediately available for analytics through Amazon Athena. A standout feature is the system’s ability to automatically adapt when database structures change—such as adding new columns—without disrupting operations or requiring manual intervention. This eliminates the technical complexity typically associated with real-time data pipelines and provides business users with the most current information for decision-making, effectively bridging the gap between operational databases and analytical systems in a cost-effective, scalable way.
This is a guest post by Supreet Padhi, Technology Architect, and Manasa Ramesh, Technology Architect at Precisely in partnership with AWS.
Enterprises rely on mainframes to run mission-critical applications and store essential data, enabling real-time operations that help achieve business objectives. These organizations face a common challenge: how to unlock the value of their mainframe data in today’s cloud-first world while maintaining system stability and data quality. Modernizing these systems is critical for competitiveness and innovation.
The digital transformation imperative has made mainframe data integration with cloud services a strategic priority for enterprises worldwide. Organizations that can seamlessly bridge their mainframe environments with modern cloud platforms gain significant competitive advantages through improved agility, reduced operational costs, and enhanced analytics capabilities. However, implementing such integrations presents unique technical challenges that require specialized solutions. Some of the challenges include converting EBCDIC data to ASCII, where the handling of data types is unique to the mainframe, such as binary data and COMP data. Data stored in Virtual Storage Access Method (VSAM) files can be quite complex due to practices to store multiple different record types in a single file. To address these challenges, Precisely—a global leader in data integrity, serving over 12,000 customers—has partnered with Amazon Web Services (AWS) to enable real-time synchronization between mainframe systems and Amazon Relational Database Service (Amazon RDS). For more on this collaboration, check out our previous blog post: Unlock Mainframe Data with Precisely Connect and Amazon Aurora.
In this post, we introduce an alternative architecture to synchronize mainframe data to the cloud using Amazon Managed Streaming for Apache Kafka (Amazon MSK) for greater flexibility and scalability. This event-driven approach provides additional possibilities for mainframe data integration and modernization strategies.
A key enhancement in this solution is the use of the AWS Mainframe Modernization – Data Replication for IBM z/OS Amazon Machine Image (AMI) available in AWS Marketplace, which simplifies deployment and reduces implementation time.
Real-time processing and event-driven architecture benefits
Real-time processing makes data actionable within seconds rather than waiting for batch processing cycles. For example, financial institutions such as Global Payments have leveraged this solution to modernize mission-critical banking operations, including payments processing. By migrating these operations to the AWS Cloud, they enhanced user experience, improved scalability and maintainability, while enabling advanced fraud detection – all without impacting the performance of existing mainframe systems. Change data capture (CDC) enables this by identifying database changes and delivering them in real time to cloud environments.
CDC offers two key advantages for mainframe modernization:
Incremental data movement – Eliminates disruptive bulk extracts by streaming only changed data to cloud targets, minimizing system impact and ensuring data currency
Real-time synchronization – Keeps cloud applications in sync with mainframe systems, enabling immediate insights and responsive operations
Solution overview
In this post, we provide a detailed implementation guide for streaming mainframe data changes from DB2z through AWS Mainframe Modernization – Data Replication for IBM z/OS AMI to Amazon MSK and then applying those changes to Amazon Relational Database Service (Amazon RDS) for PostgreSQL using MSK Connect with the Confluent JDBC Sink Connector.
By introducing Amazon MSK into architecture and streamlining deployment through the AWS Marketplace AMI, we create new possibilities for data distribution, transformation, and consumption that expand upon our previously demonstrated direct replication approach. This streaming-based architecture offers several additional benefits:
Simplified deployment – Accelerate implementation using the preconfigured AWS Marketplace AMI
Decoupled systems – Separate the concern of data extraction from data consumption, allowing both sides to scale independently
Multi-consumer support – Enable multiple downstream applications and services to consume the same data stream according to their own requirements
Extensibility – Create a foundation that can be extended to support additional mainframe data sources such as IMS and VSAM, as well as additional AWS targets using MSK Connect sink connectors
The following diagram illustrates the solution architecture.
Capture/Publisher – Connect CDC Capture/Publisher captures Db2 changes from Db2 logs using IFI 306 Read and communicates captured data changes to a target engine through TCP/IP.
Controller Daemon – The Controller Daemon authenticates all connection requests, managing secure communication between the source and target environments.
Apply Engine – The Apply Engine is a multifaceted and multifunctional component in the target environment. It receives the changes from the Publisher agent and applies the changed data to the target Amazon MSK.
Connect CDC Single Message Transform (SMT) – Performs all necessary data filtering, transformation, and augmentation required by the sink connector.
JDBC Sink Connector – As data arrives, an instance of the JDBC Sink Connector along with Apache Kafka writes the data to target tables in Amazon RDS.
This architecture provides a clean separation between the data capture process and the data consumption process, allowing each to scale independently. The use of MSK as an intermediary enables multiple systems to consume the same data stream, opening possibilities for complex event processing, real-time analytics, and integration with other AWS services.
Prerequisites
To complete the solution, you need the following prerequisites:
Create a DB cluster by using the following AWS Command Line Interface (AWS CLI) command. Replace the placeholder strings with values that correspond to your cluster’s subnet and subnet group IDs.
To create a serverless MSK cluster, complete the following steps:
Copy the following JSON and paste it into a new file create-msk-serverless-cluster.json. Replace the placeholder strings with values that correspond to your cluster’s subnet and security group IDs.
To create a Kafka topic, you need to install the Kafka CLI first. Follow these steps:
Download the binary distribution of Apache Kafka and extract the archive in folder kafka:
wget https://dlcdn.apache.org/kafka/3.9.0/kafka_2.13-3.9.0.tgz
   tar -xzf kafka_2.13-3.9.0.tgz
   ln -sfn kafka_2.13-3.9.0 kafka
To use IAM to authenticate with the MSK cluster, download the Amazon MSK Library for IAM and copy to the local Kafka library directory as shown in the following code. For complete instructions, refer to Configure clients for IAM access control.
Copy the following JSON and paste it into a new file create-custom-plugin.json. Replace the placeholder strings with values that correspond to your bucket.
Prepare the source table. Before configuring the Capture/Publisher, ensure the DEPT source table exists on your mainframe Db2 system. The table definition should match the structure defined at \$SQDATA_VAR_DIR/templates/dept.ddl. If you need to create this table on your mainframe, use the DDL from this file as a reference to ensure compatibility with the replication process.
Access the Interactive System Productivity Facility (ISPF) interface. Sign in to your mainframe system and access the AWS Mainframe Modernization – Data Repication for IBM z/OS ISPF panels through the supplied ISPF application menu. Select option 3 (CDC) to access the CDC configuration panels, as demonstrated in our previous blog post.
Add source tables for capture:
From the CDC Primary Option Menu, choose option 2 (Define Subscriptions).
Choose option 1 (Define Db2 Tables) to add source tables.
On the (Add DB2 Source Table to CAB File panel), enter a wildcard value (%) or the specific table name DEPT in the (Table Name) field.
Press Enter to display the list of available tables.
Type S next to the DEPT table to select it for replication, then press Enter to confirm.
This process is like the table selection process shown in figure 3 and figure 4 of our previous post but now focuses specifically on the DEPT table structure.
With the completion of both the Db2 Capture/Publisher setup on the mainframe and the AWS environment configuration (Amazon MSK, Apply Engine, and MSK Connect JDBC Sink Connector), you now have a fully functional pipeline ready to capture data changes from the mainframe and stream them to the MSK topic. Inserts, updates, or deletions to the DEPT table on the mainframe will be automatically captured and pushed to the MSK topic in near real time. From there, the MSK Connect JDBC Sink Connector and the custom SMT will process these messages and apply the changes to the PostgreSQL database on Amazon RDS, completing the end-to-end replication flow.
Configure Apply Engine for Amazon MSK integration
Configure the AWS side components to receive data from the mainframe and forward it to Amazon MSK. Follow these steps to define and manage a new CDC pipeline from DB2 z/OS to Amazon MSK:
Use the following command to switch to the connect user:
Copy the following content and paste it in a new file $SQDATA_VAR_DIR/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.sqd. Replace the placeholder strings with values that correspond to the DB2z endpoint:
-----------------------------------------------------------------------
   Name: DB2TOKAF: Z/OS DB2 To Kafka
   -----------------------------------------------------------------------
   SUBSTITUTION PARMS USED IN THIS SCRIPT:
   ---------------------------------------------------------------------
   JOBNAME DB2TOKAFKA;
   -----------------------------
   TABLE DESCRIPTIONS
   ---------------------------
   BEGIN GROUP SOURCE_TABLES;
   DESCRIPTION Db2SQL /var/precisely/di/sqdata/apply/DB2ZTOMSK/ddl/dept.ddl AS DEPT KEY IS DEPTNO;
   END GROUP;
   -------------------------------------------------------------
   DATASTORE SECTION
   -------------------------------------------------------------
   SOURCE DATASTORE
   DATASTORE cdc://<DB2z endpoint with port>/dbcg/DBCG_TBTSS388T6 OF UTSCDC AS CDCIN DESCRIBED BY GROUP SOURCE_TABLES;
   -- TARGET DATASTORE
   DATASTORE kafka:///pgsql-sink-topic/table_key OF JSON AS TARGET KEY IS DEPTNO DESCRIBED BY GROUP SOURCE_TABLES;
   ---------------------------------
   PROCESS INTO TARGET
   SELECT { REPLICATE(TARGET) } FROM CDCIN;
The following is an example of the output that you get when you invoke the command successfully:
SQDC042I mounting/running sqdparse with arguments:
SQDC041I args[0]:sqdparse
SQDC041I args[1]:/var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.sqd
SQDC041I args[2]:/var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.prc
SQDC000I *******************************************************
SQDC021I sqdparse Version 5.0.1-rel (Linux-x86_64)
SQDC022I Build-id 4f2d7c16728aa2e40c610db7d5a6e373476a9889
SQDC023I (c) 2001, 2025 Syncsort Incorporated. All rights reserved.
SQDC000I *******************************************************
SQDC000I
SQD0000I 2025-03-31 00:59:10
>>> Start Preprocessed /var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.sqd
000001 ----------------------------------------------------------------------
000002 -- Name: DB2TOKAF:  Z/OS DB2 To Kafka
000003 ----------------------------------------------------------------------
000004 --  SUBSTITUTION PARMS USED IN THIS SCRIPT:
000005 ----------------------------------------------------------------------
000006
000007 JOBNAME DB2TOKAFKA;
000008
000009 ----------------------------
000010 -- TABLE DESCRIPTIONS
000011 ----------------------------
000012 BEGIN GROUP SOURCE_TABLES;
000013 DESCRIPTION Db2SQL /var/precisely/di/sqdata/apply/DB2ZTOMSK/ddl/dept.ddl  AS DEPT
000014 KEY IS DEPTNO;
000015 END GROUP;
000016
000017 ------------------------------------------------------------
000018 --       DATASTORE SECTION
000019 ------------------------------------------------------------
000020
000021 -- SOURCE DATASTORE
000022 DATASTORE /var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB0A.ENGINE3.DEPT.COPY
000023           OF UTSCDC
000024           AS CDCIN
000025           DESCRIBED BY GROUP SOURCE_TABLES;
000026
000027 -- TARGET DATASTORE
000028 DATASTORE
000029           OF JSON
000030           AS TARGET
000031           KEY IS DEPTNO
000032           DESCRIBED BY GROUP SOURCE_TABLES;
000033
000034 ----------------------------------
000035
000036 PROCESS INTO TARGET
000037 SELECT
000038 {
000039     REPLICATE(TARGET)
000040 }
000041 FROM CDCIN;
<<< End Preprocessed /var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB2ZTOMSK.sqd
>>> Start Preprocessed /var/precisely/di/sqdata/apply/DB2ZTOMSK/ddl/dept.ddl
000001 CREATE TABLE DEPARTMENT
000002 (
000003    DEPTNO char(3) NOT NULL,
000004    DEPTNAME varchar(36) NOT NULL,
000005    MGRNO char(6),
000006    ADMRDEPT char(3) NOT NULL,
000007    LOCATION char(16),
000008    CONSTRAINT PK_DEPTNO PRIMARY KEY (DEPTNO)
000009 ) ;
<<< End Preprocessed /var/precisely/di/sqdata/apply/DB2ZTOMSK/ddl/dept.ddl
Number of Data Stores...................: 2
Data Store..............................: /var/precisely/di/sqdata/apply/DB2ZTOMSK/scripts/DB0A.ENGINE3.DEPT.COPY
  Alias.................................: CDCIN
  Type..................................: UTS Change Data Capture
  Number of Records.....................: 1
    Record Name.........................: DEPARTMENT
    Record Description Alias............: DEPT
    Record Description Length...........: 72
    Number of Fields....................: 5
      ................................... TYPE            OFF   LEN   XLEN  EXT
      ................................... ---------- ----- ----- ----- -----
      DEPTNO............................: CHAR(3)             0     3     3
      DEPTNAME..........................: VARCHAR(36)         3    38    38
      MGRNO.............................: CHAR(6)             7     6     6
      ADMRDEPT..........................: CHAR(3)            14     3     3
      LOCATION..........................: CHAR(16)           17    16    16
Data Store..............................:
  Alias.................................: TARGET
  Type..................................: JSON
  Number of Records.....................: 1
    Record Name.........................: DEPARTMENT
    Record Description Alias............: DEPT
    Record Description Length...........: 70
    Number of Fields....................: 5
      ................................... TYPE            OFF   LEN   XLEN  EXT
      ................................... ---------- ----- ----- ----- -----
      DEPTNO............................: CHAR(3)             0     3     3
      DEPTNAME..........................: VARCHAR(36)         3    38    38
      MGRNO.............................: CHAR(6)            41     6     6
      ADMRDEPT..........................: CHAR(3)            47     3     3
      LOCATION..........................: CHAR(16)           50    16    16
Section.................................: SQDSTP000
  Number of steps.......................: 1
SQDC017I sqdparse(pid=4023) terminated successfully
Copy the following content and paste it in a new file /var/precisely/di/sqdata_logs/apply/DB2ZTOMSK/sqdata_kafka_producer.conf. Replace the placeholder strings with values that correspond to your bootstrap server and AWS Region.
Invoke the following command to verify the data in the PostgreSQL database:
PGPASSWORD="password" psql --host=<DATABASE-HOST> --username=<user> --dbname=<database> -c "select * from \"DEPT\""
With these steps completed, you’ve successfully set up end-to-end data replication from DB2z to RDS for PostgreSQL, using AWS Mainframe Modernization – Data Replication for IBM z/OS AMI, Amazon MSK, MSK Connect, and the Confluent JDBC Sink Connector.
Cleanup
When you’re finished testing this solution, you can clean up the resources to avoid incurring additional charges. Follow these steps in sequence to ensure proper cleanup.
By capturing changed data from DB2z and streaming it to AWS targets, organizations can modernize their legacy mainframe data stores, enabling operational insights and AI initiatives. Businesses can use this solution to take advantage of cloud-based applications with mainframe data to provide scalability, cost-efficiency, and enhanced performance.
The integration of AWS Mainframe Modernization – Data Replication for IBM z/OS AMI with Amazon MSK and RDS for PostgreSQL provides an enhanced framework for real-time data synchronization that maintains data integrity. This architecture can be extended to support additional mainframe data sources such as VSAM and IMS, as well as other AWS targets. Organizations can then tailor their data integration strategy to specific business needs. Data consistency and latency challenges can be effectively managed through AWS and Precisely’s monitoring capabilities. By adopting this architecture, organizations keep their mainframe data continually available for analytics, machine learning (ML), and other advanced applications.Streaming mainframe data to AWS in near real time represents a strategic step toward modernizing legacy systems while unlocking new opportunities for innovation, with data transfers occurring in subseconds. With Precisely and AWS, organizations can effectively navigate their modernization journey and maintain their competitive advantage.
Learn more about AWS Mainframe Modernization – Data Replication for IBM z/OS AMI in the Precisely documentation. AWS Mainframe Modernization Data Replication is available for purchase in AWS Marketplace. For more information about the solution or to see a demonstration, contact Precisely.
The global real-time payments market is experiencing significant growth. According to Fortune Business Insights, the market was valued at USD 24.91 billion in 2024 and is projected to grow to USD 284.49 billion by 2032, with a CAGR of 35.4%. Similarly, Grand View Research reports that the global mobile payment market, valued at USD 88.50 billion in 2024, is expected to grow at a CAGR of 38.0% from 2025 to 2030. (Disclaimer: Third-party market research and statistics are provided for informational purposed only. AWS and IBM make no representations about the accuracy of this information.)
This rapid expansion underscores the urgency for financial institutions to modernize their payment processing infrastructure. Financial institutions often need to process high volume of transactions with near-zero latency to meet stringent service level agreements (SLAs) to support surging mobile payments volume.
However, traditional payment orchestration systems, often built on monolithic architectures, struggle to meet these demands due to latency, availability, and scalability challenges. Additionally, their reliance on on-premises infrastructure leads to higher costs and an impediment to innovation, reinforcing the need for modernization.
As sustainability becomes a priority, organizations are turning to cloud-based solutions to optimize infrastructure, reduce carbon footprints, and enhance energy efficiency. This shift provides scalability and performance, and aligns with global sustainability goals, securing the future of real-time payments.
In this post, we discuss the real-time payment orchestration framework. It uses an event-driven architecture and AWS serverless services to enhance the resiliency, efficiency, and scalability of real-time payments. By decomposing payment processing into distinct business capabilities, financial institutions can improve modularity and flexibility. Implementing tenant-based segregation helps with data isolation and security. Additionally, adopting asynchronous communication through Amazon Managed Streaming for Apache Kafka (Amazon MSK) enhances scalability and resilience.
Traditional real-time payment orchestration
Payment orchestration serves as a middleware solution, streamlining transaction processing across multiple payment methods, gateways, and financial institutions. It orchestrates key business functions such as payment authorization, payment processing, settlement and clearing, compliance and risk management, and account management for both inbound and outbound payment flows.
The following diagram depicts the high-level business capabilities supported by payment orchestrators across various payment flows, including real-time payments, digital disbursements, tax payments, wires, and more.
Detailed flowchart depicting a payment processing system with multiple components. The diagram shows primary payment types at the top (including Realtime Payments, Digital Disbursement, Credit Transfer, and Peer to Peer Payments) flowing down through core processing stages including Payment Acceptance, Execution, Clearing, Reporting, Tracking, Reversals, and Billing.
Many financial institutions adopt a tenant-based approach organized by geography due to varying clearing processes, localized regulations, and transaction requirements across AWS Regions. However, without proper separation of services, teams often continue to add region-specific logic to existing services, gradually increasing their monolithic complexity and using the same infrastructure for all payment flows.
Traditional payment systems process transactions linearly, with each step waiting for the previous one to complete. However, analysis of payment workflows reveals numerous opportunities for parallel execution:
Sanctions screening and fraud detection – Compliance and fraud checks can run simultaneously with initial routing decisions, rather than sequentially blocking all subsequent processing
Payment routing and authorization requests – When basic validations are complete, routing and authorization can proceed in parallel rather than one after another
Payment execution and ledger updates – The actual payment execution doesn’t need to wait for ledger records to be updated—these can occur concurrently
Settlement, reconciliation, and tracking – These post-transaction processes can be initiated independently as soon as the primary transaction is complete
This parallel approach can dramatically improve throughput and reduce latency compared to traditional queue-based systems where operations form a sequential chain that extends processing time and creates bottlenecks.
Most legacy payment orchestration systems rely heavily on on-premises virtual machines (VMs), leading to several challenges:
Multi-Region support for disaster recovery and multi-tenancy resulting in significant capital expenditure and operational overhead
High latency and SLA issues caused by sequential message processing and delays between globally separated data centers
Limited reusability of payment flows as monolithic architectures require region-specific changes for local clearing mechanisms and regulations, increasing complexity and costs
Scalability challenges and high memory consumption due to inefficient resource utilization and execution of irrelevant logic across regions
Complex cross-border payment routing caused by variations in clearing rules, transaction limits, and local regulations, increasing latency and routing errors
Integration challenges with diverse data formats because legacy systems rely on proprietary standards (for example, ISO 20022, SWIFT MT), complicating data conversion and compliance
High deployment complexity for new payment flows due to monolithic architectures requiring extensive region-specific modifications, slowing time to market
Environmental impact and high carbon footprint from on-premises infrastructure consuming excessive energy, whereas cloud-based approaches improve efficiency
Solution overview
To overcome these challenges, the proposed architecture embraces the following design principles to build a future-ready, real-time payment orchestration solution:
Performance at scale – Handling over 1,000 transactions per second (TPS) with consistent low latency under varying load conditions.
High availability – Achieving 99.999% uptime to meet the strict requirements of financial transactions.
Geographic resilience – Supporting global operations with region-specific compliance while maintaining consistent performance.
Cost optimization – Reducing total cost of ownership through efficient resource utilization and serverless technologies.
Security and compliance – Supporting data protection and regulatory adherence across different jurisdictions.
Operational simplicity – Streamlining deployment, monitoring, and maintenance across the payment ecosystem.
Microservices – Decomposing payment processing into distinct business capabilities, so financial institutions can improve modularity and flexibility. This microservices-based approach allows for independent scaling and development of critical components.
The following diagram depicts the high-level solution architecture for real-time payments. The existing channels using synchronous or asynchronous APIs can be modified to use edge-optimized endpoints to reduce latency.
Architecture diagram detailing an AWS-based payment orchestration platform utilizing event-driven principles. Features reusable components across two regions, with dedicated modules for payment initiation, execution, reconciliation, billing, and risk management. Implements pub/sub messaging patterns for inter-component communication and connects to enterprise systems including accounting, compliance, and analytics.
An event-driven architecture is used for payment orchestration, which handles communication through a pub/sub pattern. This architecture maintains persistent connections, improving performance of the end-to-end real-time payment processing.
The event-driven architecture for real-time payment processing allows multiple payment operations to occur simultaneously using different adaptors, as opposed to the traditional systems where payment processes are sequential and flow through a single pipeline. Payment events are distributed to specialized payment processor microservices based on their function (initiation, execution, tracking, settlements), enabling each to process independently without waiting for others to complete.
Because we’re transitioning from sequential processing to distributed, maintaining transaction traceability is crucial. The payment tracking adapters shown in the preceding diagram connect to enterprise analytics systems, creating a specialized layer for monitoring transactions. The pub/sub model allows for attaching correlation IDs to events, enabling systems to track related events across different topics and processing stages.
A standardized event schema serves as the foundation for this architecture, providing consistency across regional deployments while allowing for customization at the adapter level. This schema defines uniform event structures containing tenant-specific metadata and supports versioning to accommodate evolving requirements. By isolating region-specific variations to the adapter layer, the solution maintains core functionality while interfacing with diverse enterprise systems through configuration-driven customization rather than code changes.
For most payment processes, especially those with independent processing steps that can run in parallel, this architecture delivers net performance gains despite the topic switching overhead, particularly for complex transactions where multiple independent validations or processing steps are required.
Deployment on the AWS Cloud
The solution uses edge-optimized Amazon API Gateway for channels. An edge-optimized API endpoint routes requests to the nearest Amazon CloudFront Point of Presence (POP), which can help in cases where your clients are geographically distributed to enable efficient routing within each geographical region, enhancing global responsiveness by minimizing network round trips and making sure requests take the shortest possible path before transitioning from the public internet to the client network.
The following diagram illustrates the high-level solution architecture for real-time payments.
Comprehensive AWS payment orchestration solution implementing modern cloud-native architecture principles. Core processing logic implemented as Lambda functions covering initiation, execution, reconciliation, billing, tracking, risk management, and settlement workflows. Leverages Amazon MSK for reliable event streaming between components, with dedicated Kafka topics for each processing stage. Data persistence handled by Amazon DynamoDB, supporting cross-region operations. Architecture demonstrates AWS best practices for financial services, including regional redundancy, serverless computing, managed services, and event-driven design patterns. System integrates with external banking infrastructure and enterprise systems while maintaining separation of concerns through microservices architecture. Features built-in support for compliance monitoring, risk management, and payment tracking through specialized Lambda functions.
The solution uses Amazon MSK to implement an event-driven architecture that efficiently handles both inbound and outbound channels traffic through API requests and asynchronous message-based events. Amazon MSK communicates using a high-performance binary protocol between producers, consumers, and brokers, providing low latency and high throughput. Real-time payments are logically partitioned across multiple tenants within geographical regions—North America, EMEA, LATAM, and Asia-Pacific.
Each real-time payment tenant follows an active/active disaster recovery strategy by deploying MSK clusters across multiple AWS Regions, designed to achieve high availability and resilience. Amazon MSK offer both serverless and provisioned cluster options. The team can decide to select one or the other depending on the non-functional requirements and team expertise. Amazon MSK automatically manages partition leadership with leaders in primary Regions and followers in secondary Regions. During failover, leaders are re-elected in healthy Regions, designed to help maintain processing capabilities during regional incidents. Sticky partitioning uses consistent hashing for deterministic routing, and cooperative rebalancing enables efficient failover. Multi-AZ deployment provides zone redundancy and isolated clusters per Region for data sovereignty compliance through programmatic AWS Identity and Access Management (IAM) and virtual private cloud (VPC) boundaries.
To support seamless cross-Region replication and maintain message continuity, Amazon MSK Replicator—a fully managed feature of Amazon MSK—is used to replicate topics and synchronize consumer group offsets across clusters. MSK Replicator simplifies the process of building multi-Region Kafka applications by not needing custom code, open-source tool configuration, or infrastructure management. It automatically provisions and scales the necessary resources, so teams can focus on business logic while only paying for the data being replicated. In the event of a regional outage or failover, traffic can be automatically redirected to a healthy Region without data loss or service disruption, providing near-zero Recovery Time Objectives (RTOs) and uninterrupted operations for downstream services such as payment processors and audit trail consumers.
In addition to regional redundancy, the architecture uses an event-driven architecture to enable parallel and decoupled processing of payment transactions. Events such as transaction initiation, validation, and settlement are emitted asynchronously and consumed by various microservices independently, which drastically reduces end-to-end latency.
To process these events at scale, the architecture can use AWS Lambda, Amazon Elastic Container Service (Amazon ECS), or Amazon Elastic Kubernetes Service (Amazon EKS) depending upon non-functional requirements. Automatic scaling responds to Amazon CloudWatch metrics, and exponential backoff retry logic with dead-letter queues (DLQs) handles throttling scenarios. Circuit breakers prevent cascade failures during high error rates.
One of the key benefits of the solution is the reusability of payment flows across different regions. Although each region has its own unique compliance requirements and settlement rules, the core functionalities of real-time payments (payment authorization, payment processing, settlement and clearing) are largely similar. This reusability enables rapid deployment of payment solutions across new regions without rearchitecting the entire system. For example, the real-time payment system in the US and UK might share similar business logic for real-time gross settlement but differ in the clearing and compliance requirements. The solution treats these as bounded contexts within the microservices architecture, providing flexibility while making sure each region can handle its own specific rules and regulations.
Sustainability
AWS relentlessly innovates its infrastructure design, build, and operations to make progress towards net-zero carbon by 2040 and being water positive by 2030. Amazon MSK with AWS Graviton based instances use up to 60% less energy than comparable M5 instances, helping you achieve your sustainability goals. Lambda is inherently sustainable by design. Its serverless model makes sure compute resources are only used when needed, drastically reducing idle infrastructure and wasted energy. Instead of keeping always-on servers for infrequent tasks, Lambda provisions compute power just-in-time, achieving near-zero idle capacity.
Security and compliance in financial services
Given the sensitive nature of payment transactions and financial data, you should apply the security controls required to meet financial regulations such as AWS PCI DSS and AWS Federal Information Processing Standard (FIPS) 140-3 according to your organization’s needs.
The solution should incorporate multi-layered security controls, continuous monitoring, and automated compliance auditing to meet the rigorous expectations of banking regulators and internal risk teams. For more information, refer to Security Guidance.
Conclusion
The modernization of payment orchestration systems using an event-driven architecture and AWS serverless technologies marks a significant advancement in meeting the demands of today’s rapidly evolving financial services landscape. This solution addresses the key challenges faced by traditional payment systems while delivering substantial benefits in performance, scalability, cost optimization, global resilience, sustainability, and compliance. By using cutting-edge cloud technologies and robust security controls, financial institutions can now build a future-ready foundation that adapts to evolving business needs while maintaining the highest standards of performance, security, and reliability. As the real-time payments market continues its explosive growth, this modern architecture provides a solution that meets today’s demands and is also well-positioned to support tomorrow’s payment innovations. Organizations looking to modernize their payment infrastructure can use this blueprint to accelerate their digital transformation journey, supporting sustainable, secure, and efficient payment processing at scale in an increasingly competitive global marketplace.
The architecture presented here is for reference purposes only. IBM will work closely with you to deploy the solution in accordance with industry standards and compliance requirements.For additional resources, refer to:
IBM Consulting is an AWS Premier Tier Services Partner that helps customers who use AWS to harness the power of innovation and drive their business transformation. They are recognized as a Global Systems Integrator (GSI) for over 22 competencies, including Financial Services Consulting. For additional information, please contact an IBM Representative.
Laravel, one of the world’s most popular web frameworks, launched its first-party observability platform, Laravel Nightwatch, to provide developers with real-time insights into application performance. Built entirely on AWS managed services and ClickHouse Cloud, the service already processes over one billion events per day while maintaining sub-second query latency, giving developers instant visibility into the health of their applications.
The challenge: Delivering real-time monitoring for a global developer community
The Laravel framework powers millions of applications worldwide, serving billions of requests each month. Each request can generate potentially hundreds of observability events, such as database queries, queued jobs, cache lookups, emails, notifications, and exceptions. For Nightwatch’s launch, Laravel anticipated instant adoption from its global community, with tens of thousands of applications sending events around the clock from day one.
Laravel Nightwatch needed an architecture that could:
Ingest millions of JSON events per second from customer applications reliably.
Provide sub-second analytical queries for real-time dashboards.
Scale horizontally to handle unpredictable traffic spikes.
Deliver all of this in a cost-effective, low-maintenance manner.
The challenge was to process data on a global scale and provide deep insights into application health without compromising on a straightforward setup experience for developers.
The solution: A decoupled streaming and analytics pipeline
Laravel Nightwatch implemented a dual-database, streaming-first architecture, shown in the preceding figure, that separates transactional and analytical workloads.
Transactional workloads – user accounts, organization settings, billing, and similar workloads run on Amazon RDS for PostgreSQL.
Analytical workloads – telemetry events, metrics, query logs, and request traces are handled by ClickHouse Cloud.
Key components
The key components of the solution include the following:
Ingestion layer
Amazon API Gateway receives telemetry from Laravel agents embedded in customer applications
Lambda validates and enriches events. Validated and enriched events are published to Amazon MSK, partitioned for scalability
Streaming to analytics
ClickPipes in ClickHouse Cloud subscribe directly to MSK topics, reducing the need to build and manage extract, transform, and load (ETL) pipelines
Materialized views in ClickHouse pre-aggregate and transform raw JSON into query-ready formats
Cloudflare CDN provides low-latency delivery to global users
Why Amazon MSK and ClickHouse Cloud?
Nightwatch requires a durable, horizontally scalable, and low maintenance streaming backbone.
With Amazon MSK Express brokers, we have achieved over 1 million events per second during load testing, benefiting from low-latency, elastic scaling, and simplified operations. MSK Express brokers require no storage sizing or provisioning, scale up to 20 times faster, and recover 90% quicker than standard Apache Kafka brokers—all while enforcing best-practice defaults and client quotas for reliable performance. Its seamless integration with other AWS services—such as Lambda, Amazon Simple Storage Service (Amazon S3), and Amazon CloudWatch—made it straightforward to build a resilient, end-to-end streaming architecture.
To ingest and transform these events in real time, Nightwatch uses ClickHouse Cloud and its managed integration platform, ClickPipes. ClickHouse Cloud excels at analytical workloads by delivering up to 100 times faster query performance for analytics compared to traditional row-based databases. Its advanced compression algorithms provide up to 90% storage savings, significantly reducing infrastructure costs while maintaining high performance. With its columnar architecture and optimized execution engine, ClickHouse Cloud can query billions of rows in under 1 second, enabling Laravel Nightwatch to serve real-time dashboards and analytics at global scale.
By integrating Amazon MSK and ClickHouse using ClickPipes, Laravel also reduced the operational burden of building and managing ETL pipelines, reducing latency and complexity.
Overcoming challenges
Testing complexity
While synthetic benchmarking and test datasets yield useful results, a more realistic workload is required to rigorously test infrastructure and code before deployment to production. The team used Terraform to manage infrastructure alongside application code, creating multiple dev and test environments, and allowing them to test the platform internally with their own applications before each release.
Multi-region infrastructure
The need to cater to multiple data storage regions also brought challenges—with latency, complexity, and cost the foremost concerns. However, the AWS, ClickHouse Cloud, and Cloudflare stack made available a powerful set of networking tools and scaling options. While VPC peering, RDS replication, and global server load balancing did the heavy lifting on the networking side, the ability to scale and right-size each resource kept costs to a minimum.
Query performance at scale
Materialized views, intelligent time-series partitioning, and specialized ClickHouse codecs helped ensure that queries remained sub-second even as data volumes grew into the billions. Meanwhile, compute separation allowed distinct workloads to scale separately while accessing the same data, with clusters right-sized horizontally and vertically depending on the requirements of each load.
760,000 exceptions logged and analyzed in real time
By building on Amazon MSK and ClickHouse Cloud, we were able to scale from zero to billions of events without sacrificing performance or developer experience.
What’s next
Laravel plans to expand Nightwatch with:
More regions to cater to customers with data sovereignty requirements outside the US and EU
Broader data collection to provide even deeper insight into customers’ applications
SOC 2 certification to cater to customers with tighter compliance requirements
More advanced monitoring and analysis to identify issues before they affect users
The current architecture comfortably supports applications of all sizes, from hobby to enterprise (including a generous free tier), and is designed to handle over one trillion monthly events without performance degradation.
Conclusion
Laravel Nightwatch demonstrates how Amazon MSK, ClickHouse Cloud, and AWS serverless technologies can be combined to build a cost-effective, real-time monitoring platform at global scale. By designing for scale from day one, Laravel delivered sub-second analytics across billions of events, while maintaining the developer-friendly experience their community expects.
Organizations use streaming applications to process and analyze data in real time and adopt the Amazon MSK Connect feature of Amazon Managed Streaming for Apache Kafka (Amazon MSK) to run fully managed Kafka Connect workloads on AWS. Message brokers like Apache Kafka allow applications to handle large volumes and diverse types of data efficiently and enable timely decision-making and instant insights. It’s crucial to monitor the performance and health of each component to help ensure the seamless operation of data streaming pipelines.
Amazon MSK is a fully managed service that simplifies the deployment and operation of Apache Kafka clusters on AWS. It simplifies building and running applications that use Apache Kafka to process streaming data. Amazon MSK Connect simplifies the deployment, monitoring, and automatic scaling of connectors that transfer data between Apache Kafka clusters and external systems such as databases, file systems, and search indices. Amazon MSK Connect is fully compatible with Kafka Connect and supports Amazon MSK, Apache Kafka, and Apache Kafka compatible clusters. Amazon MSK Connect uses a custom plugin as the container for connector implementation logic.
Custom MSK connect plugins use Java Management Extensions (JMX) to expose runtime metrics. While Amazon MSK Connect sends a set of connect metrics to Amazon CloudWatch, it currently does not support exporting the JMX metrics emitted by the connector plugins natively. These metrics can be exported by modifying the custom connect plugin code directly, but it requires maintenance overhead because the plugin code needs to be modified every time it’s updated. In this post, we demonstrate an optimal approach by extending a custom connect plugin with additional modules to export JMX metrics and publish them to CloudWatch as custom metrics. These additional JMX metrics emitted by the custom connectors provide rich insights into their performance and health of the connectors. In this post, we demonstrate how you can export the JMX metrics for Debezium connector when used with MSK Connect.
Understanding JMX
Before we dive deep into exporting JMX metrics, let’s understand how JMX works. JMX is a technology that you can use to monitor and manage Java applications. Key components involved in JMX monitoring are:
Managed beans (MBeans) are Java objects that represent the metrics of the Java application being monitored. They contain the actual data points of the resources being monitored.
JMX server creates and registers the MBeans with the PlatformMBeanServer. The Java application that is being monitored acts as the JMX server and exposes the MBeans.
MBeanServer or JMX registry is the central registry that keeps track of all the registered MBeans in the JMX server. It is the access point for all the MBeans within the Java virtual machine (JVM).
JMXConnectorServer acts as a bridge between the JMX client and the JMX server and enables remote access to the exposed MBeans. JMXConnectorServerFactory creates and manages the JMXConnectorServer. It allows for the customization of the server’s properties and uses the JMXServiceURL to define the endpoint where the JMX client can connect to the JMX server.
JMXServiceURL provides the necessary information such as the protocol, host, and port for the client to connect to the JMX server and access the desired MBeans.
JMX client is an external application or tool that connect to the JMX server to access and monitor the exposed metrics.
JMX monitoring involves the steps shown in the following figure:
JMX monitoring steps include:
The Java application acting as the JMX server creates and configures MBeans for the desired metrics.
JMX server registers the MBeans with the JMX registry.
JMXConnectorServerFactory creates the JMXConnectorServer that defines the JMXServiceURL that provides the entry point details for the JMX client.
JMXClient connects to the JMX registry in the JMX server using the JMXServiceURL and the JMXConnectorServer.
The JMX server handles client requests, interacting with the JMX registry to retrieve the MBean data.
Solution overview
This method of wrapping supported Kafka connectors with custom code that exposes connector-specific operational metrics enables teams to get better insights by correlating various connector metrics with cloud-centered metrics in monitoring systems such as Amazon CloudWatch. This approach enables consistent monitoring across different components of the change data capture (CDC) pipeline, ultimately feeding metrics into unified dashboards while respecting each connector’s architectural philosophy. The consolidated metrics can be delivered to CloudWatch or the monitoring tool of your choice including partner specific application performance management (APM) tools such as Datadog, New Relic, and so on.
We have the working implementation of this same approach with two popular connectors: Debezium source connector and MongoDB Sink Connector. You can find the Github sample and ready to use plugins built for each in the repository. Review the README file for this custom implementation for more details.
For example, our custom implementation for the MongoDB Sink Connector adds a metrics export layer that calculates critical performance indicators such as latest-kafka-time-difference-ms – which measures the latency between Kafka message timestamps and connector processing time by subtracting the connector’s current clock time from the last received record’s timestamp. This custom wrapper around the MongoDB Sink Connector enables exporting relevant JMX metrics and publishing them as custom metrics to CloudWatch. We’ve open sourced this solution on GitHub, along with a ready-to-use plugin and detailed configuration guidance in the README.
CDC is the process of identifying and capturing changes made in a database and delivering those changes in real time to a downstream system. Debezium is an open source distributed platform built on top of Apache Kafka that provides CDC functionality. It provides a set of connectors to track and stream changes from databases to Kafka.
In the next section, we dive deep into the implementation details of how to export JMX metrics from Debezium MySQL Connector deployed as a custom plugin in Amazon MSK Connect. The connector plugin takes care of creating and configuring the MBeans and registering them with the JMX registry.
The following diagram shows the workflow of using Debezium MySQL Connector as a custom plugin in Amazon MSK Connect for CDC from an Amazon Aurora MySQL-Compatible Edition data source.
MySQL binary log (binlog) is enabled in Amazon Aurora for MySQL to record all the operations in the order in which they are committed to the database.
The Debezium connector plugin component of the MSK Connect custom plugin continuously monitors the MySQL database, captures the row-level changes by reading the MySQL bin logs, and streams them as change events to Kafka topics in Amazon MSK.
We’ll build a custom module to enable JMX monitoring on the Debezium connector. This module will act as a JMX client to retrieve the JMX metrics from the connector and publish them as custom metrics to CloudWatch.
The Debezium connector provides three types of metrics in addition to the built-in support for default Kafka and Kafka Connect JMX metrics.
Snapshot metrics provide information about connector operation while performing a snapshot.
Streaming metrics provide information about connector operation when the connector is reading the binlog.
Schema history metrics provide information about the status of the connector’s schema history.
In this solution, we export the MilliSecondsBehindSource streaming metrics emitted by the Debezium MySQL connector. This metricprovides the number of milliseconds that the connector is lagging behind the change events in the database.
Prerequisites
Following are the prerequisites you need:
Access to the AWS account where you want to set up this solution.
You have set up the source database and MSK cluster by following this setup instructions in the MSK Connect workshop.
Create a custom plugin
Creating a custom plugin for Amazon MSK Connect for the solution involves the following steps:
Create a custom module: Create a new Maven module or project that will contain your custom code to:
Enable JMX monitoring in the connector application by starting the JMX server.
Create a Remote Method Invocation (RMI) registry to enable the access to the JMX metrics to the clients.
Create a JMX metrics exporter to query the JMX metrics by connecting to the JMX server and push the metrics to CloudWatch as custom metrics.
Schedule to run the JMX metrics exporter at a configured interval.
Package and deploy the custom module as an MSK Connect custom plugin.
Create a connector using the custom plugin to capture CDC from the source, stream it and validate the metrics in Amazon CloudWatch.
This custom module extends the connector functionality to export the JMX metrics without requiring any changes in the underlying connector implementation. This helps ensure that upgrading the custom plugin requires only upgrading the plugin version in the pom.xml of the custom module.
Let’s deep dive and understand the implementation of each step mentioned above.
1. Create a custom module
Create a new Maven project with dependencies on Debezium MySQL Connector to enable JMX monitoring, Kafka Connect API for configuration, and CloudWatch AWS SDK to push the metrics to CloudWatch. Set up a JMX connector server to enable JMX monitoring: To enable JMX monitoring, the JMX server needs to be started at the time of initializing the connector. This is usually done by setting the environment variables with JMX options as described in Monitoring Debezium. In the case of an Amazon MSK Connect custom plugin, JMX monitoring is enabled programmatically at the time of connector plugin initialization. To achieve this:
Extend the MySqlConnector class and override the start which is the connector’s entry point to execute custom code.
public class DebeziumMySqlMetricsConnector extends MySqlConnector{
@Override
	public void start(Map<String, String> props) {
In the start method of the custom connector class (DebeziumMySqlMetricsConnector) that we are creating, set the following parameters to allow customization of the JMX Server properties by retrieving connector configuration from a config file.
connect.jmx.port – The port number on which the RMI registry needs to be created. JMXConnectorServer would listen to the incoming connections on this port.
database.server.name – Name of the database that is the source for the CDC.
It also retrieves the CloudWatch configuration related properties that will be used while pushing the JMX metrics to CloudWatch.
cloudwatch.namespace.name – CloudWatch NameSpace to which the metrics need to be pushed as custom metrics
cloudwatch.region – CloudWatch Region where the custom namespace is created in your AWS account
Create an RMI registry on the specified port (connectJMXPort). This registry is used by the JMXConnectorServer to store the RMI objects corresponding to the MBeans in the JMX registry. This allows the JMX clients to look up and access the MBeans on the PlatformMBeanServer.
LocateRegistry.createRegistry(connectJMXPort);
Retrieve the PlatformMBeanServer and construct the JMXServiceURL which is in the format service:jmx:rmi://localhost/jndi/rmi://localhost:<<jmx.port>>/jmxrmi. Create a new JMXConnectorServer instance using the JMXConnectorServerFactory and the JMXServiceURL and start the JMXConnectorServer instance.
Implement JMX metrics exporter: Create a JMX client to connect to the JMX server, query the MilliSecondBehindSource metric from the JMX server, convert it into the required format, and export it to CloudWatch.
Connect to the JMX Server using the JMXConnectorFactory and JMXServiceURL
Query the MBean object that holds the corresponding metric, for example, MilliSecondsBehindSource, and retrieve the metric value using sample code provided in msk-connect-custom-plugin-jmx. (you can choose one or more metrics).
Schedule the execution of your JMX metrics exporter at regular intervals.
Export metrics to CloudWatch: Implement the logic to push relevant JMX metrics to CloudWatch. You can use the AWS SDK for Java to interact with the CloudWatch PutMetricData API or use the CloudWatch Logs subscription filter to ingest the metrics from a dedicated Kafka topic.
For more information, see the sample implementation for the custom module in aws-samples in GitHub. This sample also provides custom plugins packaged with two different versions of Debezium MySQL connector (debezium-connector-mysql-2.5.2.Final-plugin and debezium-connector-mysql-2.7.3.Final-plugin) and the following steps would explain the steps to build a custom plugin using your custom code.
2. Package the custom module and Debezium MySQL connector as a custom plugin
Build and package the Maven project with the custom code as a JAR file and include the JAR file in the debezium-connector-mysql-2.5.2.Final-plugin folder downloaded from maven repo. Package the updated debezium-connector-mysql-2.5.2.Final-plugin as a ZIP file (Amazon MSK Connect accepts custom plugins in ZIP or JAR format). Alternatively, you can use the prebuiltcustom-debezium-mysql-connector-plugin.zip available in GitHub.
Choose the Debezium connector version (2.5 or 2.7) that fits your requirement.
When you have to upgrade to a new version of the Debezium MySQL connector, you can update the version of the dependency and build the custom module and deploy it. By doing this, you can maintain the custom plugin without modifying the original connector code. The GitHub samples provide ready-to-use plugins for two Debezium connector versions. However, you can follow the same approach to upgrade to the latest connector version as well.
Create a custom plugin in Amazon MSK
If you have set up your AWS resources by following the Getting Started lab, open Amazon S3 console and locate the bucket msk-lab-${ACCOUNT_ID}-plugins-bucket/debezium .
Upload the custom plugin created in the previous section custom-debezium-mysql-connector-plugin.zip to msk-lab-${ACCOUNT_ID}-plugins-bucket/debezium, as shown in the following figure.
Switch to the Amazon MSK console and choose Custom plugins in the navigation pane. Choose Create custom plugin and, browse the S3 bucket that you created above and select the custom plugin ZIP file you just uploaded.
Enter custom-debezium-mysql-connector-plugin for the plugin name. Optionally, enter a description and choose Create Custom Plugin.
After a few seconds you should see the plugin is created and the status is Active.
Customize the worker configuration for the connector by following the instructions in the Customize worker configuration lab.
3. Create an Amazon MSK connector
The next step is to create an MSK connector.
From the MSK section choose Connectors, then choose Create connector. Choose custom-debezium-mysql-connector-plugin from the list of Custom plugins, then choose Next.
Enter custom-debezium-mysql-connector in the Name textbox, and a description for the connector.
Select the MSKCluster-msk-connect-lab from the listed MSK clusters. From the Authentication dropdown, select IAM.
Copy the following configuration and paste it in the connector configuration textbox.
Replace the <Your Aurora MySQL database endpoint>, <Your Database Password>, <Your MSK Bootstrap Server Address>, and <Your CloudWatch Region>placeholders with the corresponding details for the resources in your account.
Review the topic.prefix, database.user, topic.prefix, database.server.id, database.server.name, database.port, database.include.listparameters in the configuration. These parameters are configured with the values used in the workshop. Update them with the details corresponding to your configuration if you have customized it in your account.
Note that the connector.classparameter is updated with the qualified name of the subclass of MySqlConnector class that you created in the custom module.
The connect.jmx.portparameter specifies the default port to start the JMX server. You can configure this to any available port.
5. Follow the remaining instructions from the Create MSK Connector lab and create the connector. Verify that the connector status changes to Running.
Debezium MySQL custom connector version (2.7.3) provides additional flexibility to configure optional properties that can be added to your MSK connector configuration and selectively include and exclude metrics to emit to CloudWatch. The following are the example configuration properties that can be used with version 2.7.3 :
cloudwatch.debezium.streaming.metrics.include – A comma-separated list of streaming metrics type that must be exported to CloudWatch as custom metrics.
cloudwatch.debezium.streaming.metrics.exclude – Specify a comma-separated list of streaming metrics types to exclude from being sent to CloudWatch as custom metrics.
Similarly include and exclude properties for snapshot metrics type are cloudwatch.debezium.snapshot.metrics.include and cloudwatch.debezium.snapshot.metrics.exclude
Include and exclude properties for schema history metrics type are cloudwatch.debezium.schema.history.metrics.include and cloudwatch.debezium.schema.history.metrics.exclude
Review the GitHub README file for more details on the use of these properties with MSK connector configurations.
Verify the replication in the Kafka cluster and CloudWatch metrics
Follow the instructions in the Verify the replication in the Kafka cluster lab to set up a client and make changes to the source DB and verify that the changes are captured and sent to Kafka topics by the connector.
To verify that the connector has published the JMX metrics to CloudWatch, go to the CloudWatch console and choose Metrics in the navigation pane, then choose All Metrics. Under Custom namespace, you can see MSK_Connect with database name as the dimension. Select the database name to view the metrics.
Select the MilliSecondBehindSource metric with statistic as Average in the Graphed Metric to plot the graph. You can verify that the MilliSecondBehindSource metric value is greater than zero whenever any operation is being performed on the source database and returns to zero during the idle time.
Clean up
Delete the resources that you created such as the Aurora DB, Amazon MSK Cluster and connectors by following the instructions at Cleanup in the Amazon MSK Connect lab if you have been following along to set up the solution on your account.
Conclusion
In this post, we showed you how to extend the Debezium MySQL connector plugin with an additional module to export the JMX metrics to CloudWatch as custom metrics. As a next step, you can create a CloudWatch alarm to monitor the metrics and take remediation actions when the alarm is triggered. In addition to exporting the JMX metrics to CloudWatch, you can export these metrics to third-party applications such as Prometheus or DataDog using CloudWatch Metric Streams. You can follow a similar approach to export the JMX metrics of other connectors from MSK Connect. You can learn more about creating your own connectors by visiting the Connector Developer Guide and how to deploy them as custom plugins in the MSK Connect documentation.
About the authors
Jaydev Nath is a Solutions Architect at AWS, where he works with ISV customers to build secure, scalable, reliable, and cost-efficient cloud solutions. He brings strong expertise in building SaaS architecture on AWS with a focus on Generative AI and data analytics technologies to help deliver practical, valuable business outcomes for customers.
David John Chakram is a Principal Solutions Architect at AWS. He specializes in building data platforms and architecting seamless data ecosystems. With a profound passion for databases, data analytics, and machine learning, he excels at transforming complex data challenges into innovative solutions and driving businesses forward with data-driven insights.
Sharmila Shanmugam is a Solutions Architect at Amazon Web Services. She is passionate about solving the customers’ business challenges with technology and automation and reduce the operational overhead. In her current role, she helps customers across industries in their digital transformation journey and build secure, scalable, performant and optimized workloads on AWS.
This post is co-written with Hyeonho Kim, Jinhyeong Seo and Minjae Kwon from Karrot.
In Part 1 of this series, we discussed how Karrot developed a new feature platform, which consists of three main components: feature serving, a stream ingestion pipeline, and a batch ingestion pipeline. We discussed their requirements, the solution architecture, and feature serving using a multi-level cache. In this post, we share the stream and batch ingestion pipelines and how they ingest data into an online store from various event sources.
Solution overview
The following diagram illustrates the solution architecture, as introduced in Part 1.
Stream ingestion
Stream ingestion is the process of collecting data from various event sources in real time, transforming it into features, and storing them. It consists of two main components:
Consumer – These are pods located on Amazon Elastic Kubernetes Service (Amazon EKS) that process events according to feature group specifications defined in the feature platform and load them into the database and remote cache.
Consumers handle not only the source events, but also re-published events. When loading features, they are performed by considering different strategies, such as write-through and write-around, and are loaded in detail considering cardinality, data size, and access patterns.
Most features are generated based on two types of events: events that occur due to real-time user actions, and asynchronous events that occur due to state changes in user and article data. These events and features have an M:N relationship, meaning one event can be the source of multiple features, and one feature can be generated based on multiple events.
The following diagram illustrates the architecture of the stream ingestion pipeline.
To efficiently handle M:N relationships, a structure was needed to receive events and distribute them to multiple feature processing logics. Two core components were designed for this purpose:
Dispatcher – Receives events from multiple consumer groups and propagates them to relevant feature processing logic
Aggregator – Processes events received from the dispatcher into actual features
This stream processing pipeline enables real-time feature generation and storage.
Message broker optimization: Fast at-least-once delivery
The feature platform processes up to 25,000 events per second, including user behavior log events, at high speed. However, when worker traffic surges, event processing failures or infrastructure failures occasionally cause event loss. To solve this problem, the existing automatic commit mode was changed to manual commit in Amazon MSK. This allows events to be committed only when they are definitely processed, and failed events are sent to a separate retry topic and postprocessed through a dedicated worker.
However, processing large volumes of events synchronously with manual commit resulted in approximately 10 times slower processing speed and increased latency. Although consumer group resources were available, simply increasing the number of partitions in Amazon MSK wasn’t a solution due to team-specific partitioning permissions. The platform designed parallel processing within single partitions and implemented a custom consumer supporting retry functionality. The core of the implementation is to read as many messages from the partition as the fetch size at a time and process them by spawning worker threads in parallel for each message. When processing is complete, the offsets of successful messages are sorted and a manual commit is performed for the largest offset, and failed messages are republished to the retry topic. This enables parallel processing even in a single partition, and the concurrency can be controlled automatically. As a result, the event processing speed is faster than the existing automatic commit method, and it is stably processed without delay even when the number of events increases.
Stream processing
The stream ingestion pipeline performs only simple extract, transform, and load (ETL) logic and validation. There were already many requirements for complex stream processing in the feature platform, and a separate service was created to accommodate them. The feature platform didn’t address these requirements for the following reasons:
The purpose of stream ingestion in the feature platform is to collect and store features in real time, whereas the main purpose of stream processing is to process data.
Not all features require complex processing. We decided that it wasn’t appropriate to make the entire stream collection process complicated for some features.
The result data of stream processing could be used outside the feature platform, and there were requirements to consider this. Therefore, creating a separate service was more suitable for Karrot’s situation.
Additionally, some source data didn’t exist in AWS, which could have resulted in significant additional costs if everything was handled within the feature platform.
Although it’s a separate service from the feature platform, the following is a brief introduction to how the feature platform uses data through stream processing:
Various content embedding cases – We perform stream processing using models, and use various contents (articles, images, and so on) as input values to pre-trained models to create embeddings. These embeddings are stored in the feature platform and used as features during recommendation to improve recommendation quality.
Rich feature generation cases – Some of the processed data is further processed using large language models (LLMs) for use as features. One example is predicting which category a specific second-hand product belongs to and using this prediction value as a feature.
Batch ingestion
Batch ingestion is responsible for processing and storing large amounts of data into features in batches. This is divided into a cron job that runs periodically and a backfill job that loads large amounts of data one time.
For this purpose, AWS Batch based on AWS Fargate is used. AWS Batch jobs running on Fargate are provisioned independently from the other environments, enabling safe large-scale processing. For example, even if more than 1,000 servers or 10,000 vCPUs are used for backfilling large amounts of data, they are operated separately from the other services and can be operated efficiently with a usage-based billing method.
When adding new features, batch loading of past data or periodic loading of large amounts of data is one of the core functions of the feature platform. The main requirements considered in the design are as follows:
It must be able to process large amounts of data.
It must be able to start at the time desired by the user and finish the work within an appropriate time.
It must have low operating costs. It should be a managed service if possible, and it’s better if there is less additional work or specific domain knowledge for operation. Also, it should reuse existing service code as much as possible.
Complex operations for features or the configuration of Directed Acyclic Graphs (DAGs) are not necessarily required.
There were several options to choose from, such as Apache Airflow, but AWS Batch was chosen to avoid over-engineering considering the operating cost according to the current requirements.
The following diagram illustrates the architecture of the batch ingestion pipeline.
The key components are as follows:
Scheduler – It extracts the targets that need to perform the batch jobs according to the specifications such as FeatureGroupSpec and IngestionSpec written by the user on the feature platform, and registers the corresponding job specifications to an AWS Batch job (submit job).
AWS Batch – The jobs submitted by the scheduler are executed using the preconfigured job queue and computing environment. In the case of AWS Batch, you can configure a Fargate environment separately from the other production services, so that even if you provision large-scale resources and perform tasks, you can perform tasks stably without affecting the other production services.
Future improvements for batch ingestion
The current configuration works well and reliably, but there are some areas for improvement:
No DAG support – The initial feature platform performed relatively simple tasks, such as parsing batch data sources, converting them to the feature schema, and storing them. However, as the platform became more advanced, more complex operations became necessary, and therefore support for DAG configurations that can process features by sequentially performing various dependent jobs became necessary.
Manual configuration for parallel processing – Currently, when processing large-scale data in parallel, the worker must manually estimate the number of jobs to be processed in parallel and provide it in the specification, and the scheduler performs a submit job in parallel based on this. This method is based purely on experience, and in order for the system to become more advanced, the system must be able to automatically abstract and optimize the appropriate level of parallel processing.
Limited AWS Batch monitoring usability – AWS Batch monitoring has some limitations, such as jobs don’t transition from Runnable to Running state, a lack of appropriate notification systems for such cases, and the inability to directly check failed jobs through URL parameters when receiving alerts. These aspects should be improved from an operational convenience perspective.
Results
As of February 2025, Karrot has addressed the major problems mentioned in the early stages of feature platform development:
Decoupling recommendation logic from flea market server – The recommendation system now uses the feature platform across more than 10 different recommendation spaces and services.
Securing scalability of features used in recommendation logic – With more than 1,000 high-quality and rich features acquired from various services such as flea market, advertisements, local jobs, and real estate, we are contributing to the advancement of recommendation logic and making it straightforward for all Karrot engineers to explore and add features.
Maintaining the reliability of feature data sources – Through the feature platform, we are providing reliable data using a consistent schema and ingestion pipeline.
Karrot engineers are continuously improving the user experience by advancing recommendations through high-quality features through the feature platform. This has contributed to increasing click-through rates by 30% and conversion rates by 70% compared to before by recommending articles that users might be interested in.
This was possible because the AWS services used in the feature platform were firmly supporting it. Amazon DynamoDB has amazing scalability in all aspects of read, write, and storage, so it was possible to handle dynamically changing workloads without incurring separate operating costs. Amazon ElastiCache showed highly reliable service stability, so we could use it with confidence. In addition, it was straightforward and stable to scale up, down, in, and out, so it was possible to reduce the operational burden. It also seamlessly integrated with the ecosystem of Redis OSS, so we could use open source ecosystems such as Redis Exporter. Amazon MSK also supports reliable operation and seamless integration with the Apache Kafka ecosystem, making the development and operation of the feature platform effortless.
Furthermore, working with AWS enables cost-efficient operations based on their various support and expertise. Recently, we had an over-provisioning problem with our ElastiCache cluster. Right-sizing our ElastiCache cluster with various experts (including Solutions Architects) made it possible to optimize ElastiCache costs by nearly 40%. Such technical human resources from AWS have been invaluable in operating the feature platform using AWS products.
Conclusion
In this series, we discussed how Karrot built a feature platform on AWS. We believe that by combining AWS services and our experience, you can develop and operate a feature store without difficulty by modifying it to suit your company’s requirements. Try out this implementation and let us know your thoughts in the comments.
Organizations must often deal with a vast array of data formats and sources in their data analytics workloads. This range of data types, such as structured relational data, semi-structured formats like JSON and XML and even binary formats like Protobuf and Avro, has presented new challenges for companies looking to extract valuable insights.
Protocol Buffers (protobuf) has gained significant traction in industries that require efficient data serialization and transmission, particularly in streaming data scenarios. Protobuf’s compact binary representation, language-agnostic nature, and strong typing make it an attractive choice for companies in sectors such as finance, gaming, telecommunications, and ecommerce, where high-throughput and low-latency data processing is crucial.
Although protobuf offers advantages in efficient data serialization and transmission, its binary nature poses challenges when it comes to analytics use cases. Unlike formats like JSON or XML, which can be directly queried and analyzed, protobuf data requires an additional deserialization step to convert it from its compact binary format into a structure suitable for processing and analysis. This extra conversion step introduces complexity into data analytics pipelines and tools. It can potentially slow down data exploration and analysis, especially in scenarios where near real-time insights are crucial.
In this post, we explore an end-to-end analytics workload for streaming protobuf data, by showcasing how to handle these data streams with Amazon Redshift Streaming Ingestion, deserializing and processing them using AWS Lambda functions, so that the incoming streams are immediately available for querying and analytical processing on Amazon Redshift.
The solution provides a solid foundation for handling protobuf data in Amazon Redshift. You can further enhance the architecture to support schema evolution by incorporating AWS Glue Schema Registry. By integrating the AWS Glue Schema Registry, you can make sure your Lambda function uses the latest schema version for deserialization, even as your data structure changes over time. However, for the purpose of this post and to maintain simplicity, we focus on demonstrating how to invoke Lambda from Amazon Redshift to convert protobuf messages to JSON format, which serves as a solid foundation for handling binary data in near real-time analytics scenarios.
Solution overview
The following architecture diagram describes the AWS services and features needed to set up a fully functional protobuf streaming ingestion pipeline for near real-time analytics.
The workflow consists of the following steps:
An Amazon Elastic Compute Cloud (Amazon EC2) event producer generates events and forwards them to a message queue. The events are created and serialized using protobuf.
A Redshift cluster (provisioned or serverless), in which a materialized view with an external schema is configured, points to the message queue. For this post, we use Amazon Redshift Serverless.
A Lambda protobuf deserialization function is triggered by Amazon Redshift during ingestion and deserializes protobuf data into JSON data.
Schema
To showcase protobuf’s deserialization functionality, we use a sample protobuf schema that represents a financial trade transaction. This schema will be used across the AWS services mentioned in this post.
In this section, we focus on the materialized view definition that makes it possible to deserialize protobuf data. Our example focuses on streaming ingestion from Amazon MSK. Typically, the materialized view ingests the Kafka metadata fields and the actual data (kafka_value) like in the following example:
CREATE MATERIALIZED VIEW trade_events AUTO REFRESH YES AS
SELECT
     kafka_partition,
     kafka_offset,
     kafka_timestamp_type,
     kafka_timestamp,
     kafka_key,
     JSON_PARSE(kafka_value) as Data,
     kafka_headers
FROM
     "dev"."msk_external_schema"."entity"
WHERE
     CAN_JSON_PARSE(kafka_value)
When the incoming kafka_value is of type JSON, you can apply the built-in JSON_PARSE function and create a column of type SUPER so you can directly query the data.
Creating or updating our Amazon Redshift Lambda UDF is straightforward, as illustrated in the following code. Additional examples are available in the GitHub repo.
CREATE OR REPLACE EXTERNAL FUNCTION f_deserialize_protobuf(VARCHAR(MAX))
RETURNS VARCHAR(MAX) IMMUTABLE
LAMBDA 'f-redshift-deserialize-protobuf' IAM_ROLE ':RedshiftRole';
Because Lambda functions don’t (at the time of writing) accept binary data as input, you must first convert incoming binary data to its hex representation, prior to calling the function. You can do this by using the TO_HEX Amazon Redshift function. Considering the hex conversation and with the Lambda UDF available, you can now use it in your materialized view definition:
CREATE MATERIALIZED VIEW trade_events AUTO REFRESH YES AS
SELECT
       kafka_partition,
       kafka_offset,
       kafka_timestamp_type,
       kafka_timestamp,
       kafka_key,
       kafka_value,
       kafka_headers,
       JSON_PARSE(f_deserialize_protobuf(to_hex(kafka_value)))::super as json_data
FROM
       "dev"."msk_external_schema"."entity";
Lambda layer
Lambda functions require access to appropriate protobuf libraries, so that deserialization can take place. You can implement this through a Lambda layer. The layer is provided as a zip file, respecting the following folder structure, and contains the protobuf library, its dependencies, and user-provided code inside the custom folder, which includes the protobuf generated classes:
python
      custom
      google
      Protobuf-4.25.2.dist-info
Because we implemented the Lambda functions in Python, the root folder of the zip file is the python folder. For additional languages, refer to the documentation on how to properly structure your folder structure.
Lambda function
A Lambda function converts incoming protobuf records to JSON records. As a first step, you must import your custom classes from the lambda Layer custom folder:
# Import generated protobuf classes
 from custom import trade_pb2
You can now deserialize incoming hex encoded binary data to objects. This is implemented in a two-step process. The first step is to decode the hex encoded binary data:
 # convert incoming hex data to binary
binary_data = bytes.fromhex(record)
Next, you instantiate the protobuf defined classes and execute the actual deserialization process using the protobuf library method ParseFromString:
 # Instantiate class
trade_event = trade_pb2.Trade()

# Deserialize into class
trade_event.ParseFromString(binary_data)
After you run deserialization and instantiate your objects, you can convert to other formats. In our case, we serialize into JSON format, so that Amazon Redshift ingests the JSON content in a single field of type SUPER:
# Serialize into json
elems = trade_event.ListFields()
fields = {}
for elem in elems:
       fields[elem[0].name] = elem[1]
json_elem = json.dumps(fields)
Combining these steps together, the Lambda function should look as follows:
import json

# Import the generated protobuf classes
from custom import trade_pb2

def lambda_handler(event, context):

    results = []

    recordSets = event['arguments']
    for recordSet in recordSets:
        for record in recordSet:

            # convert incoming hex data to binary data
            binary_data = bytes.fromhex(record)

            # Instantiate class
            trade_event = trade_pb2.Trade()

            # Deserialize into class
            trade_event.ParseFromString(binary_data)

            # Serialize into json
            elems = trade_event.ListFields()
            fields = {}
            for elem in elems:
                fields[elem[0].name] = elem[1]
            json_elem = json.dumps(fields)

            # Append to results
            results.append(json_elem)

    print('OK')

    return json.dumps({"success": True,"num_records": len(results),"results": results})
Batch mode
In the preceding code sample, Amazon Redshift is calling our function in batch mode, meaning that a number of records are sent during a single Lambda function call. More specifically, Amazon Redshift is batching records into the arguments property of the request. Therefore, you must loop through the incoming array of data and apply your deserialization logic per record. At the time of writing, this behavior is internal to Amazon Redshift and can’t be configured or controlled through a configuration option. An Amazon Redshift streaming consumer client will read new records on the message queue since the last time it read. The following is a sample of the payload the Lambda handler function receives:
With your data stored in Amazon Redshift after the deserialization process, you can now execute queries against your streaming data and directly gain insights. In this section, we present some sample queries to illustrate functionality and behavior.
Examine lag query
To examine the difference between the most recent timestamp value of our streaming source vs. the current date/time (wall clock), we calculate the most recent point in time at which we ingested data. Because streaming data is expected to flow into the system continuously, this metric also reveals the ingestion lag between our streaming source and Amazon Redshift.
select top 1
      (GETDATE() - kafka_timestamp) as ingestion_lag
from
      trade_events
order by
      kafka_timestamp desc
Examine content query: Fraud detection on an incoming stream
By applying the query functionality available in Amazon Redshift, we can discover behavior hidden in our data in real time. With the following query, we try to match opposite trade volumes played by different users during the last 5 minutes that result in a zero sum game and could support a potential fraud detection concept:
select
json_data.volume,
LISTAGG(json_data.userid::int, ', ') as users,
LISTAGG(json_data.pair::int, ', ') as pairs
from
        trade_events
where
        trade_events.kafka_timestamp >= DATEADD(minute, -5, GETDATE())
group by
        json_data.volume
having
        sum(json_data.pair) = 0
and min(abs(json_data.pair)) = max(abs(json_data.pair))
and count(json_data.pair) > 1
This query is a rudimentary example of how we can use live data to protect systems from fraudsters.
Examine content query: Join with non-streaming data
Having our protobuf records streaming in Amazon Redshift makes it possible to join streaming with non-streaming data. A typical example is combining incoming trades with user information data already recorded in the system. In the following query, we join the incoming stream of trades with user information, like email, to get a list of possible alerts targets:
select
    user_info.email
from
    trade_events
inner join
    user_info
on user_info.userId = trade_events.json_data.userid
where
    trade_events.json_data.volume > 1000
and trade_events.kafka_timestamp >= DATEADD(minute, -5, GETDATE())
Conclusion
The ability to effectively analyze and derive insights from data streams, regardless of their format, is crucial for data analytics. Although protobuf offers compelling advantages for efficient data serialization and transmission, its binary nature can pose challenges and perhaps impact performance when it comes to analytics workloads. The solution outlined in this post provides a robust and scalable framework for organizations seeking to gain valuable insights, detect anomalies, and make data-driven decisions with agility, even in scenarios where high-throughput and low-latency processing is crucial. By using Amazon Redshift Streaming Ingestion in conjunction with Lambda functions, organizations can seamlessly ingest, deserialize, and query protobuf data streams, enabling near real-time analysis and insights.
Konstantinos Tzouvanas is a Senior Enterprise Architect on AWS, specializing in data science and AI/ML. He has extensive experience in optimizing real-time decision-making in High-Frequency Trading (HFT) and applying machine learning to genomics research. Known for leveraging generative AI and advanced analytics, he delivers practical, impactful solutions across industries.
Marios Parthenios is a Senior Solutions Architect working with Small and Medium Businesses across Central and Eastern Europe. He empowers organizations to build and scale their cloud solutions with a particular focus on Data Analytics and Generative AI workloads. He enables businesses to harness the power of data and artificial intelligence to drive innovation and digital transformation.
Pavlos Kaimakis is a Senior Solutions Architect at AWS who helps customers design and implement business-critical solutions. With extensive experience in product development and customer support, he focuses on delivering scalable architectures that drive business value. Outside of work, Pavlos is an avid traveler who enjoys exploring new destinations and cultures.
John Mousa is a Senior Solutions Architect at AWS. He helps power and utilities and healthcare and life sciences customers as part of the regulated industries team in Germany. John has interest in the areas of service integration, microservices architectures, as well as analytics and data lakes. Outside of work, he loves to spend time with his family and play video games.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
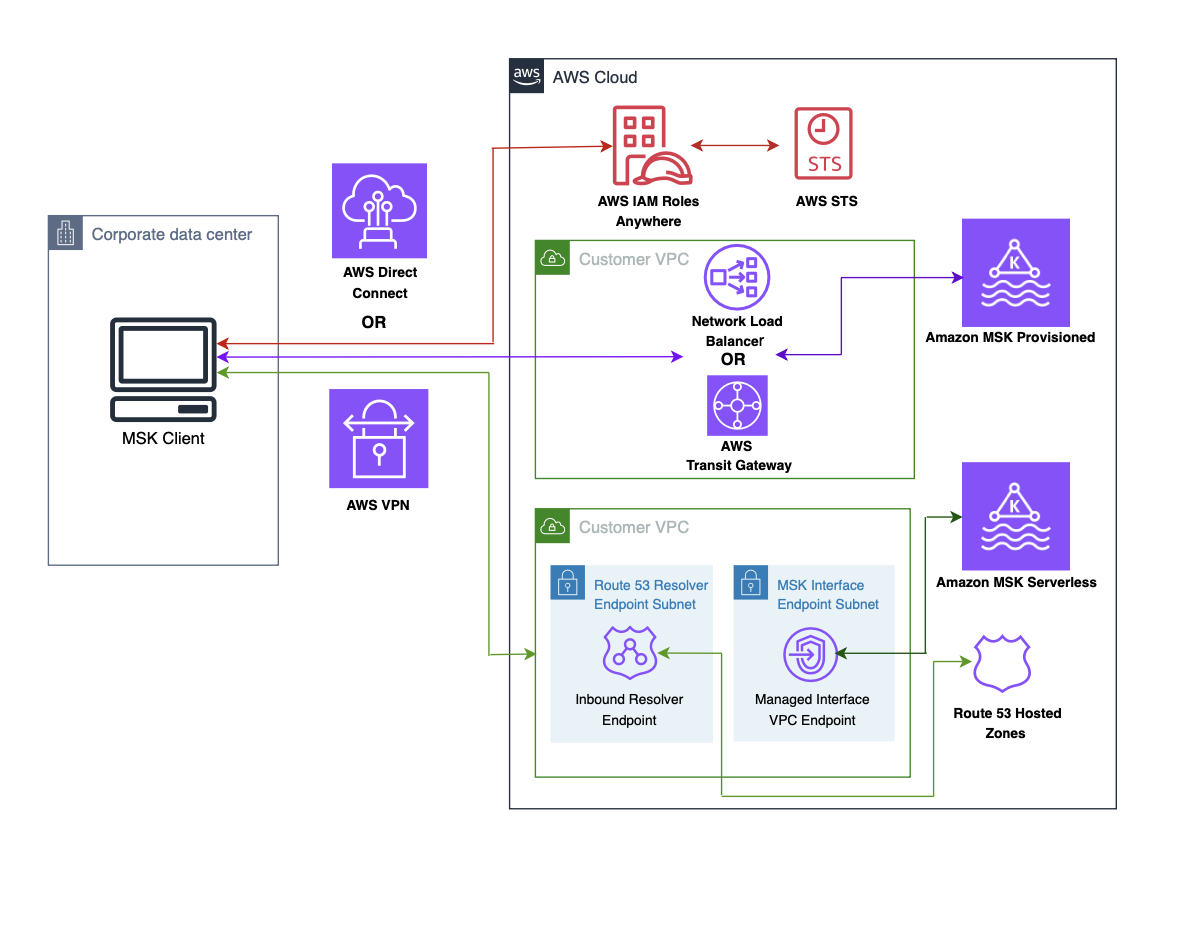
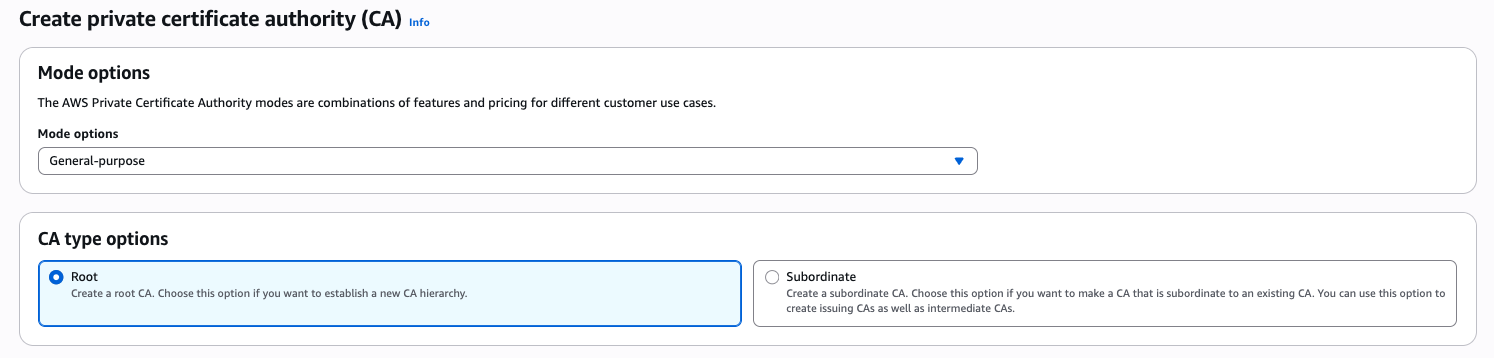


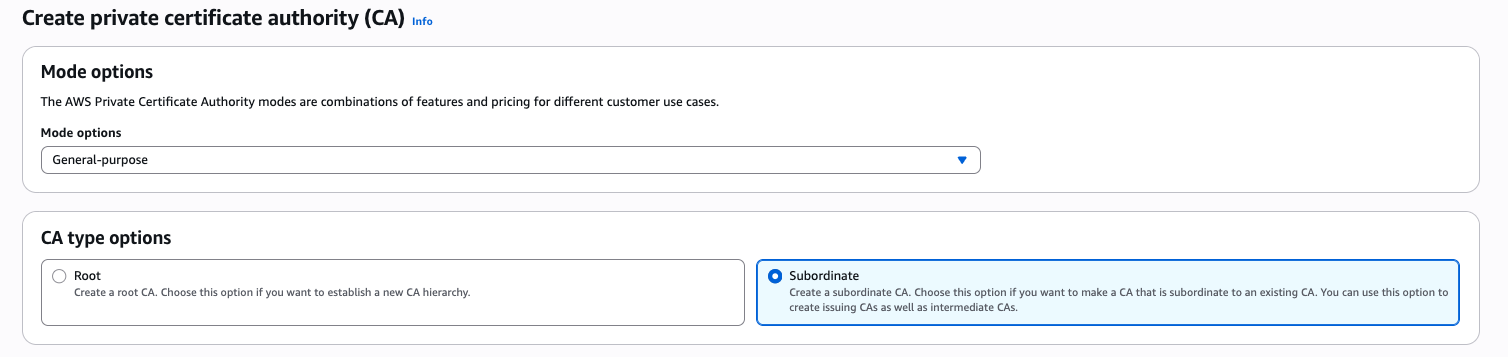
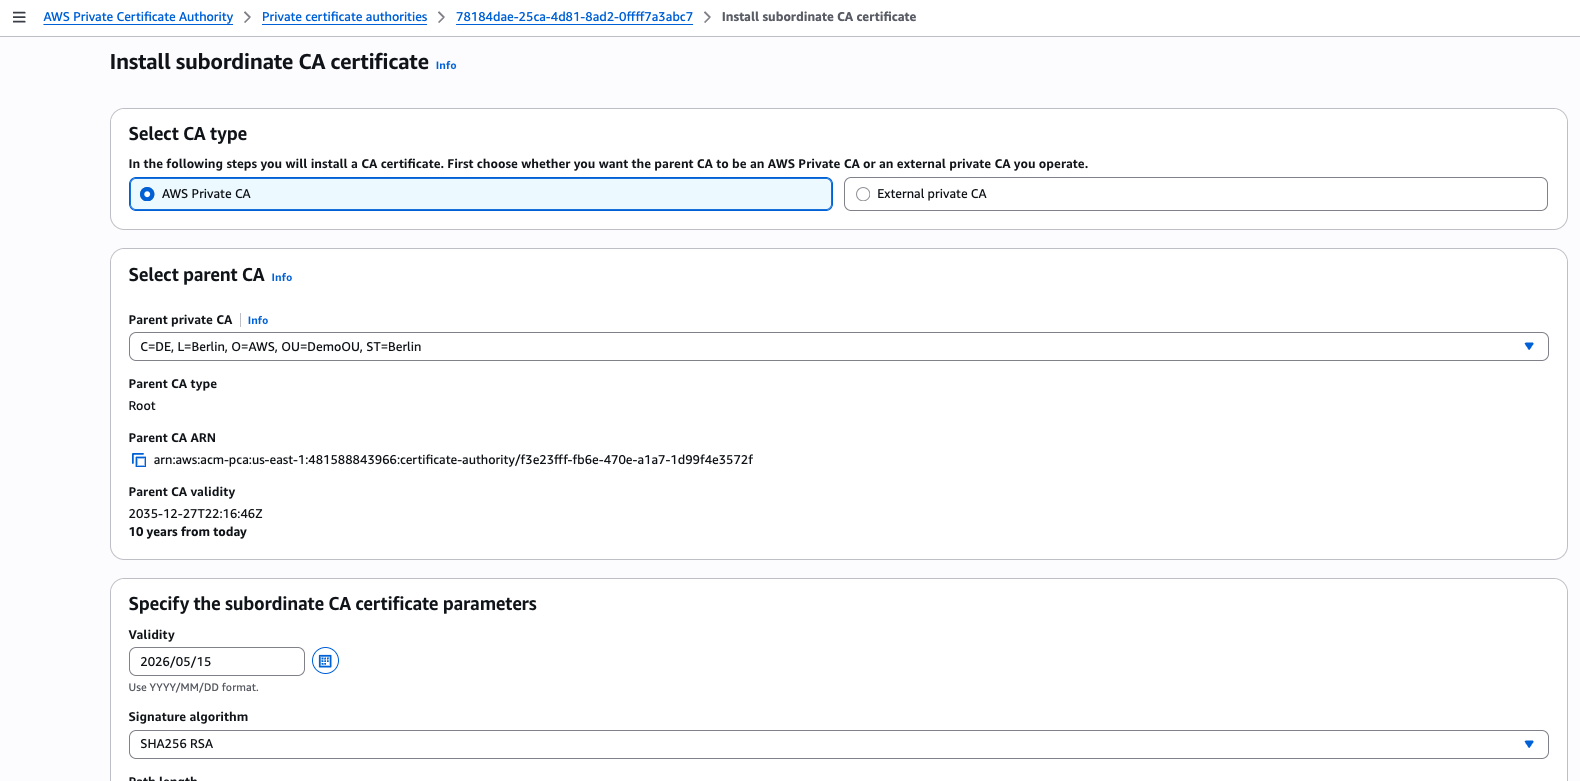
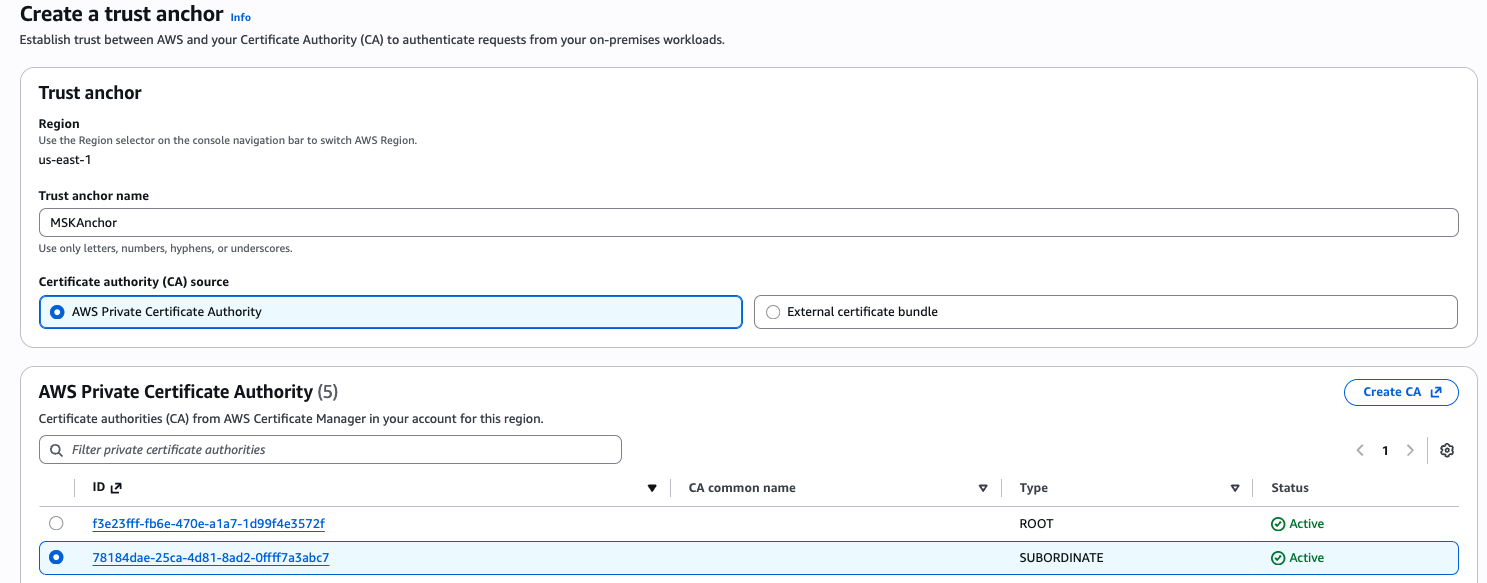
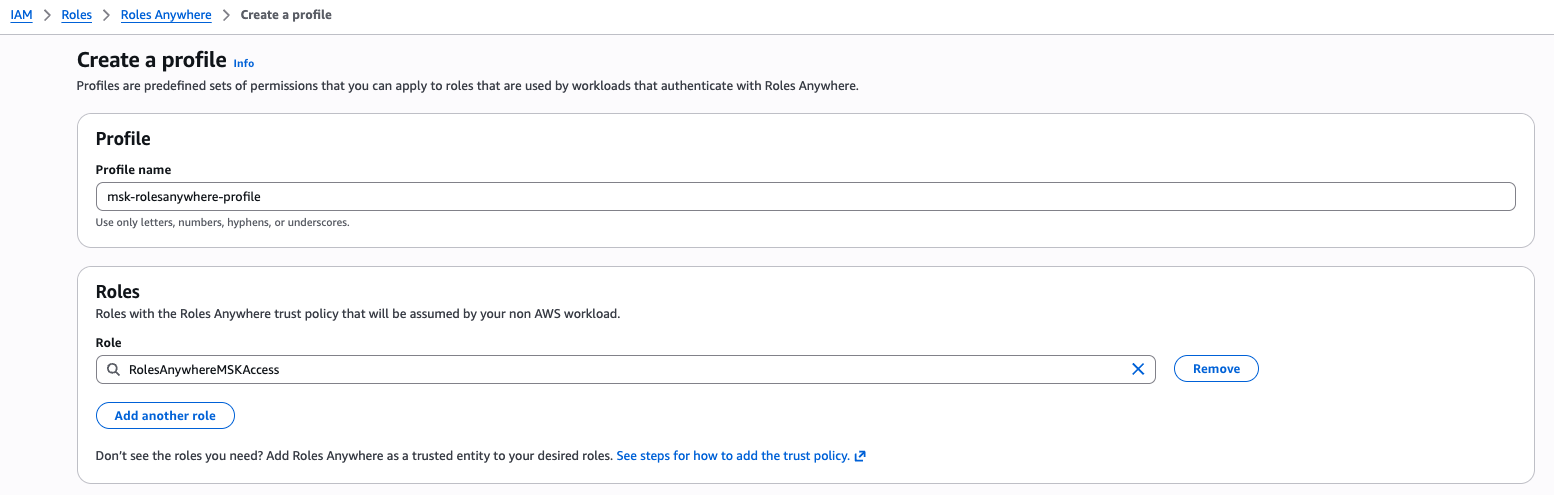


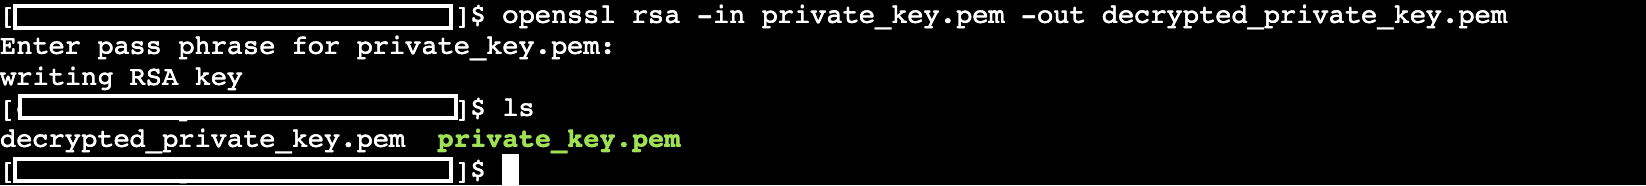
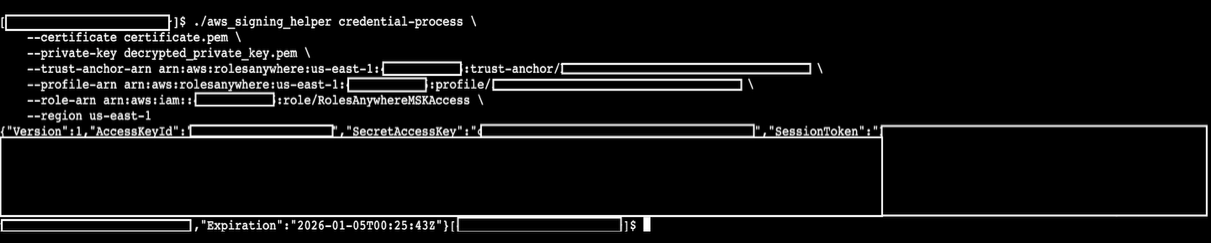

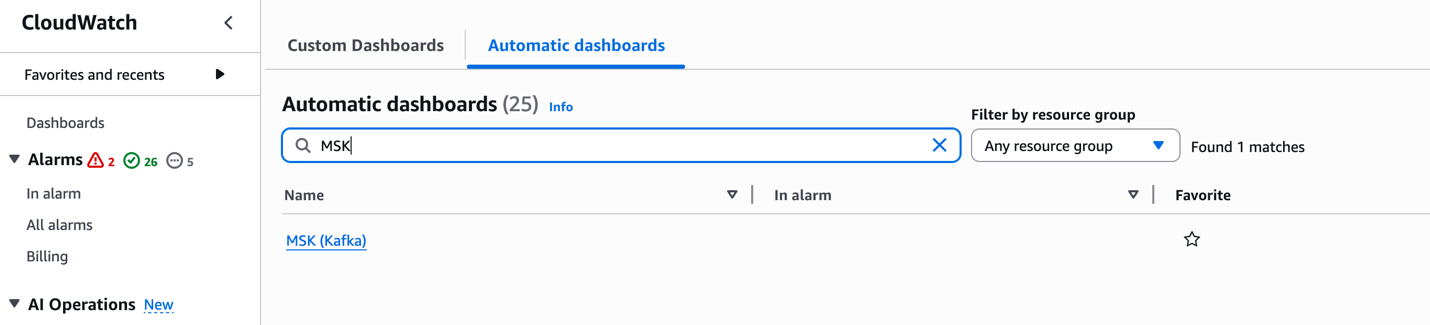
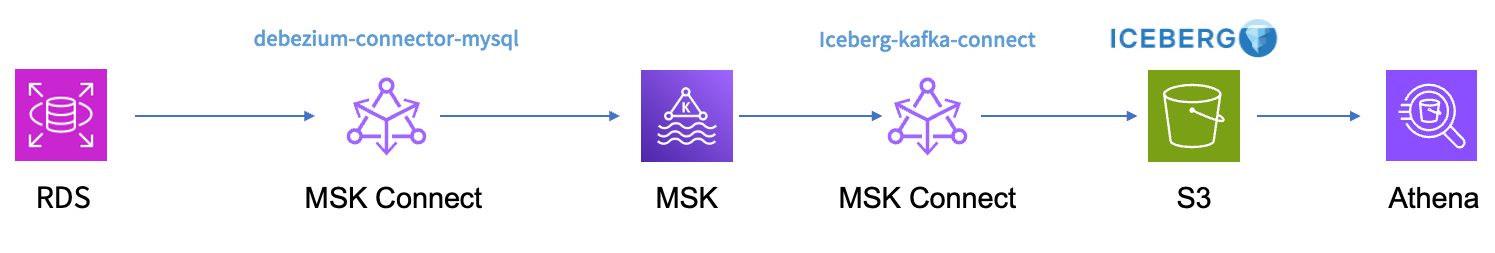
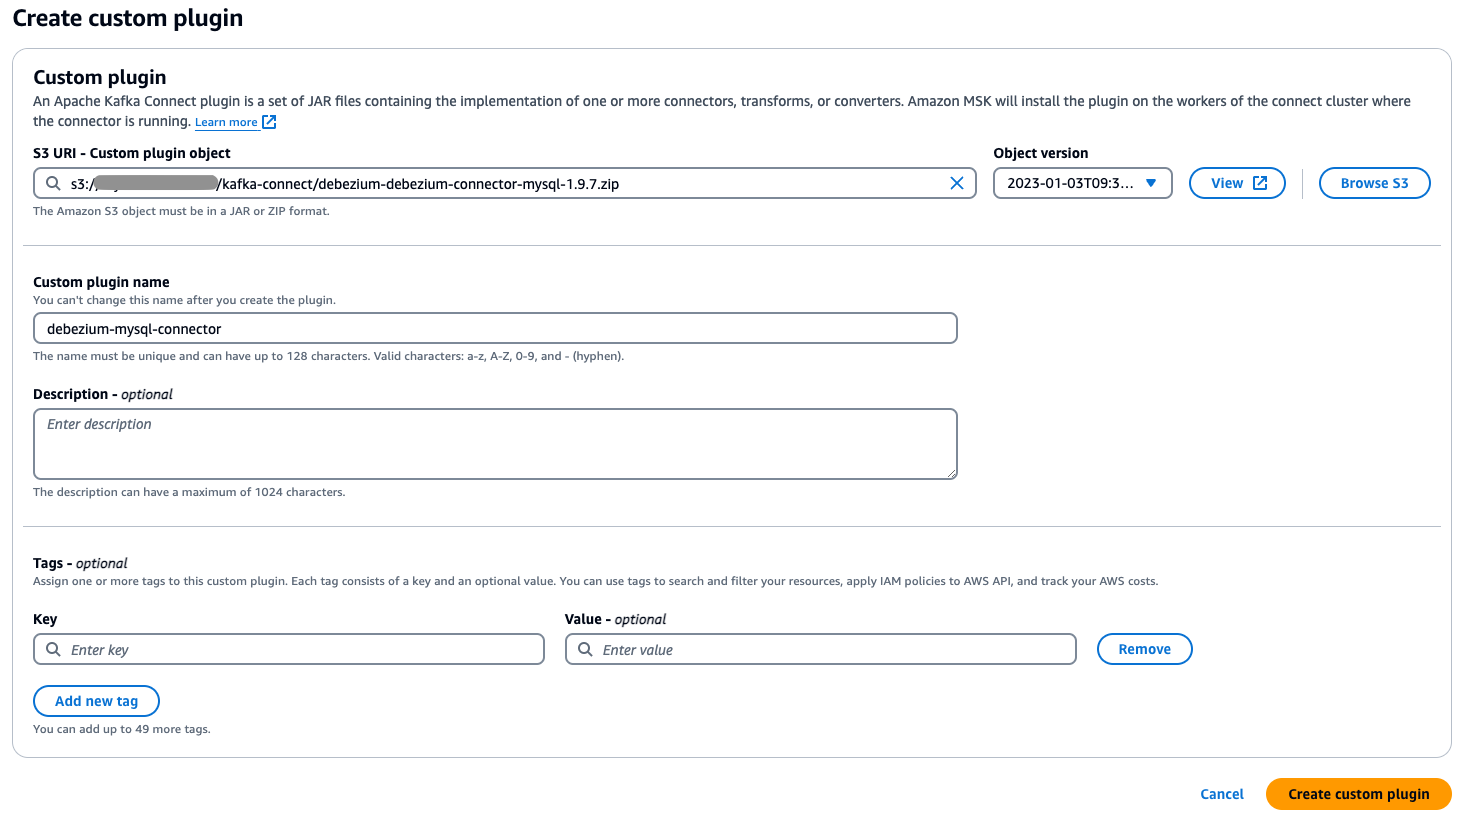
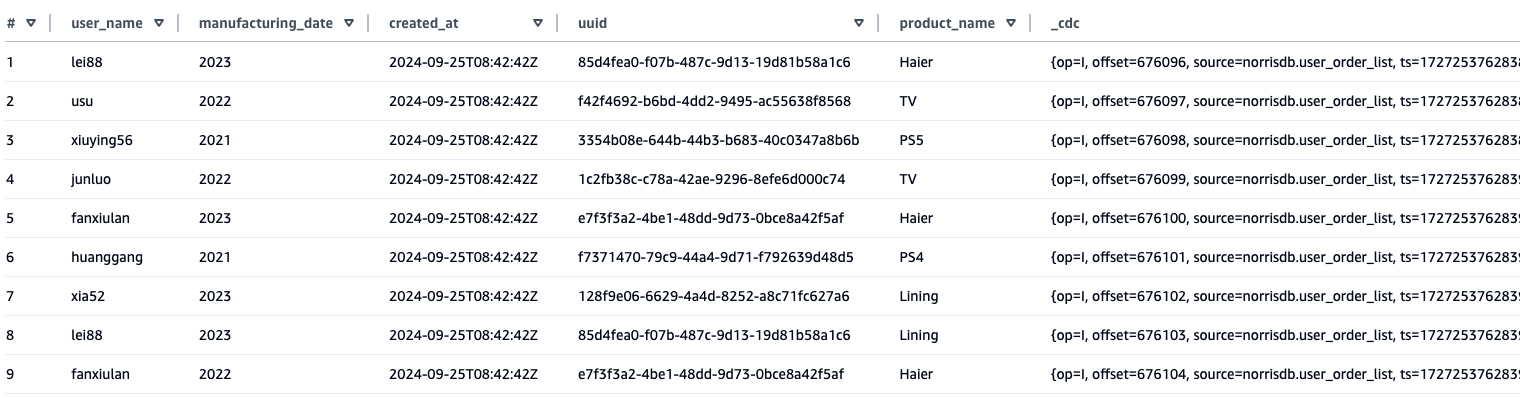
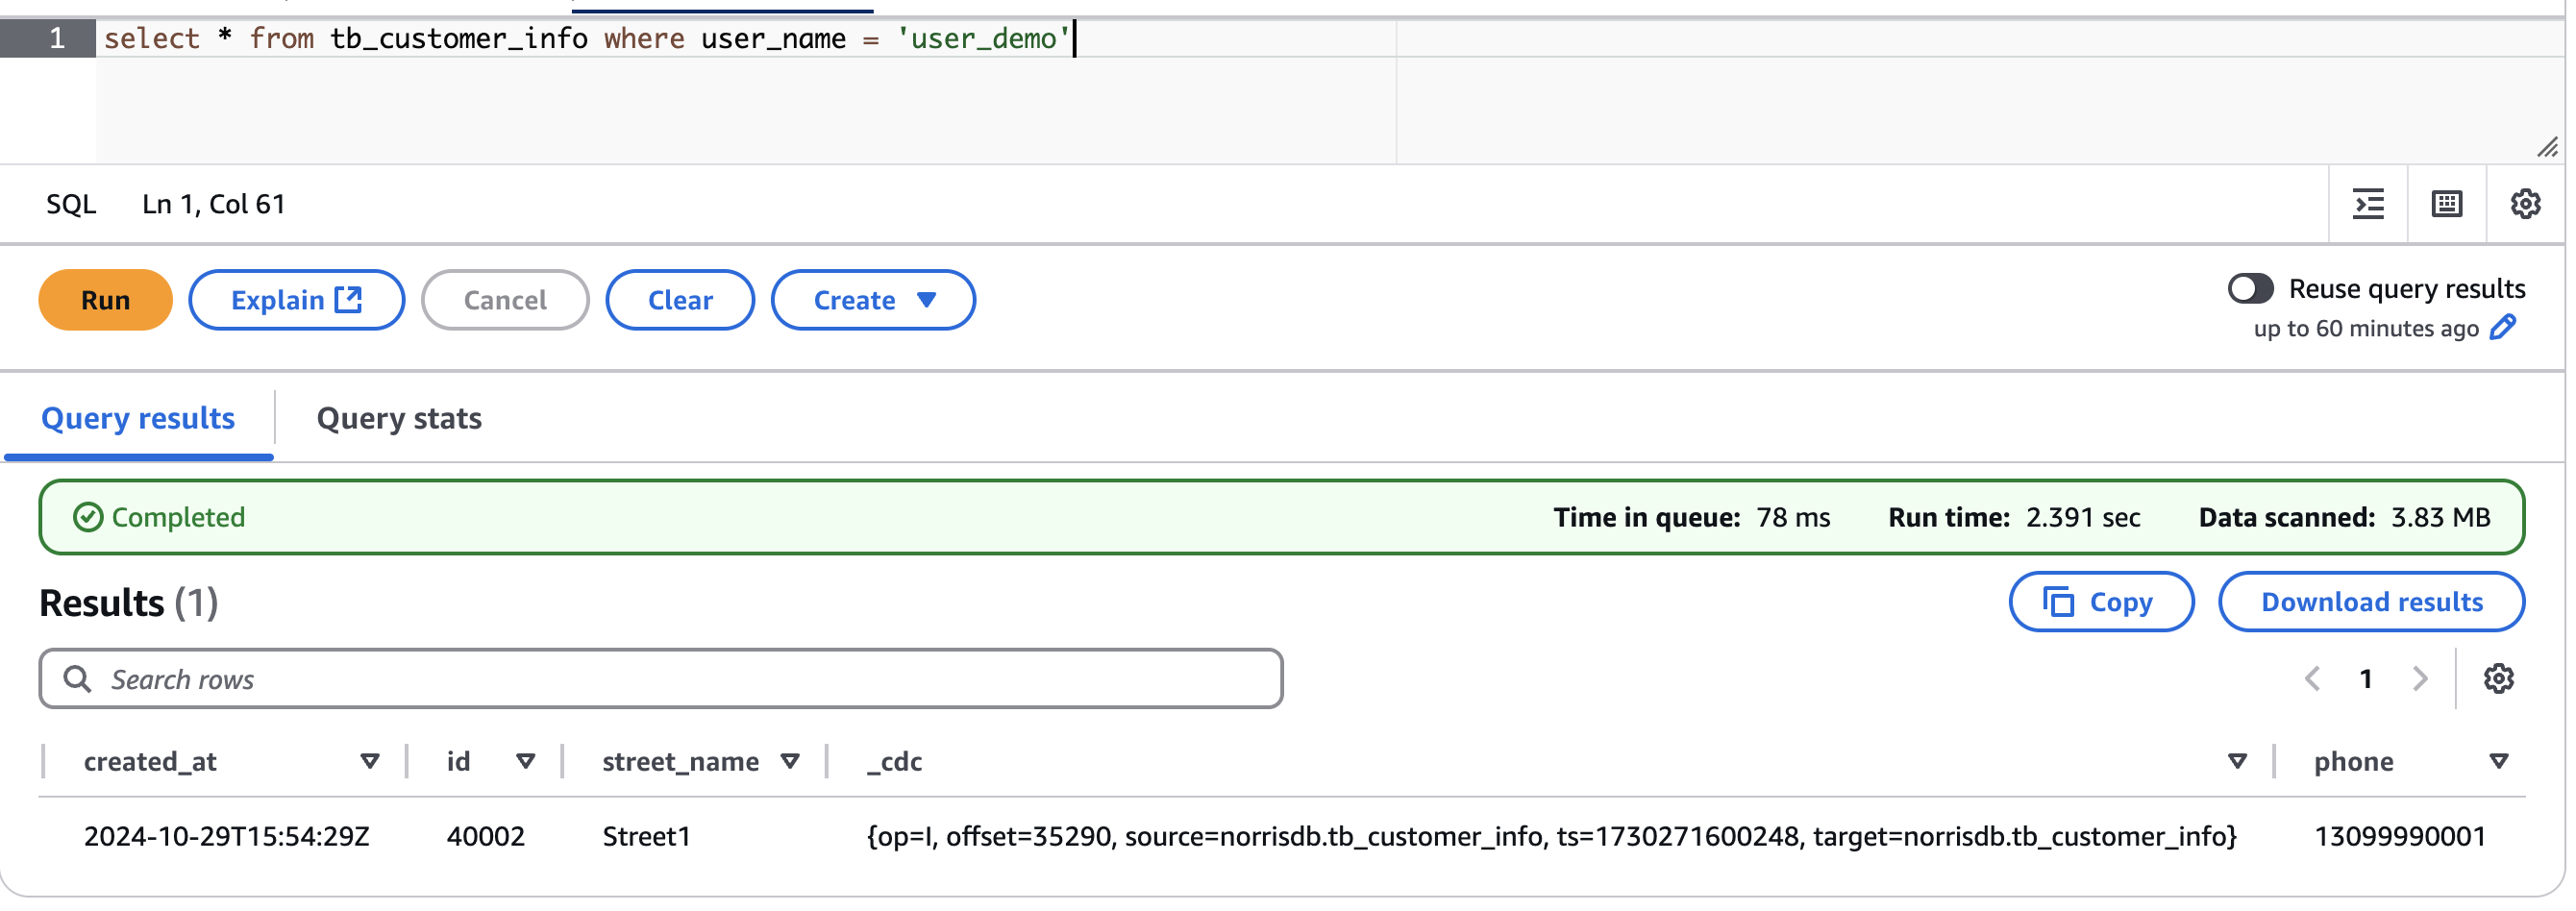
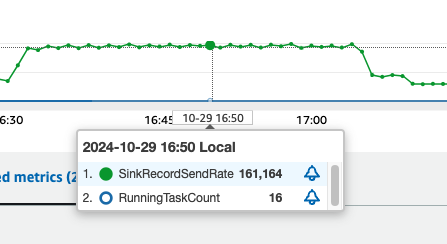
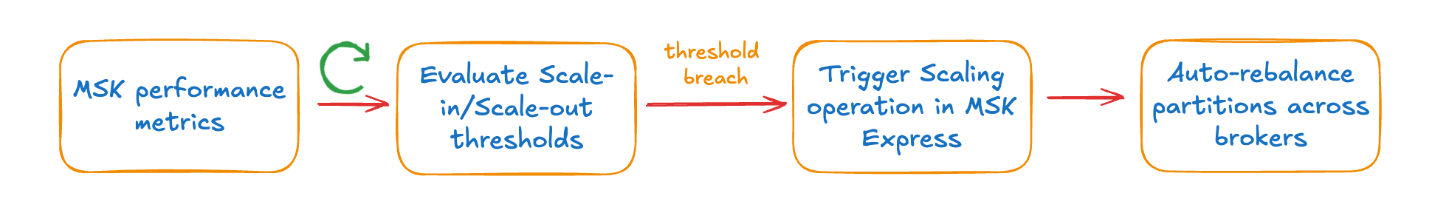
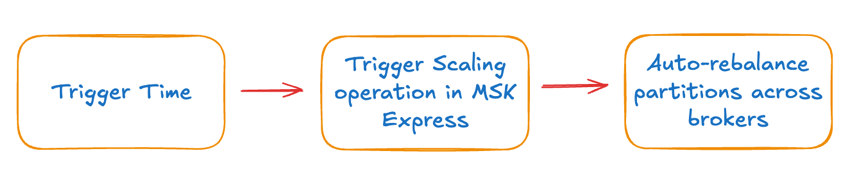
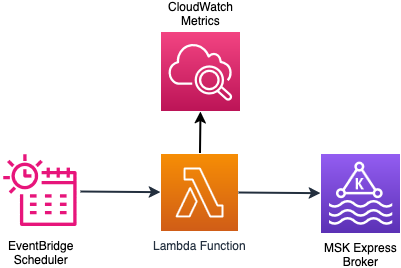
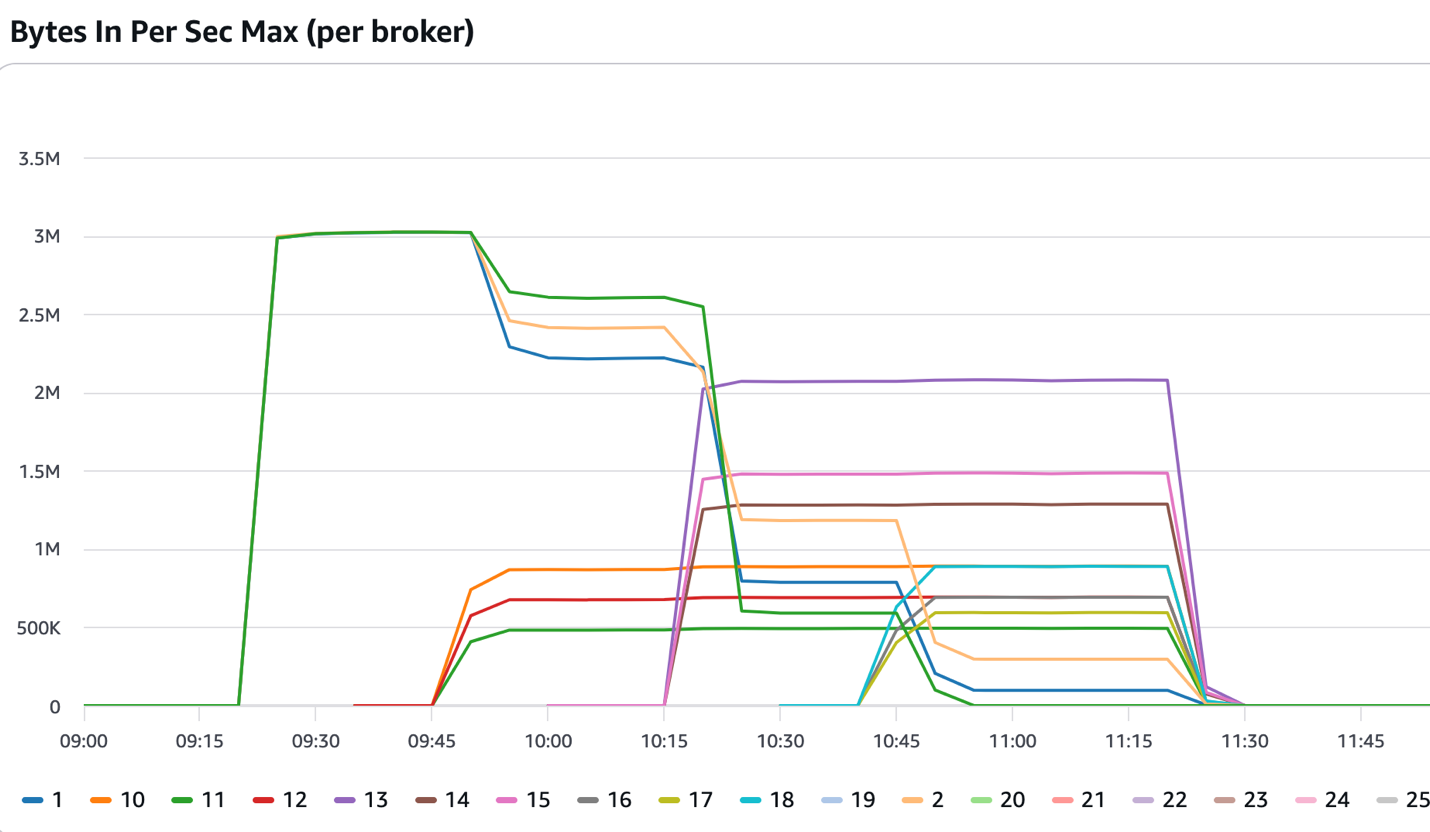
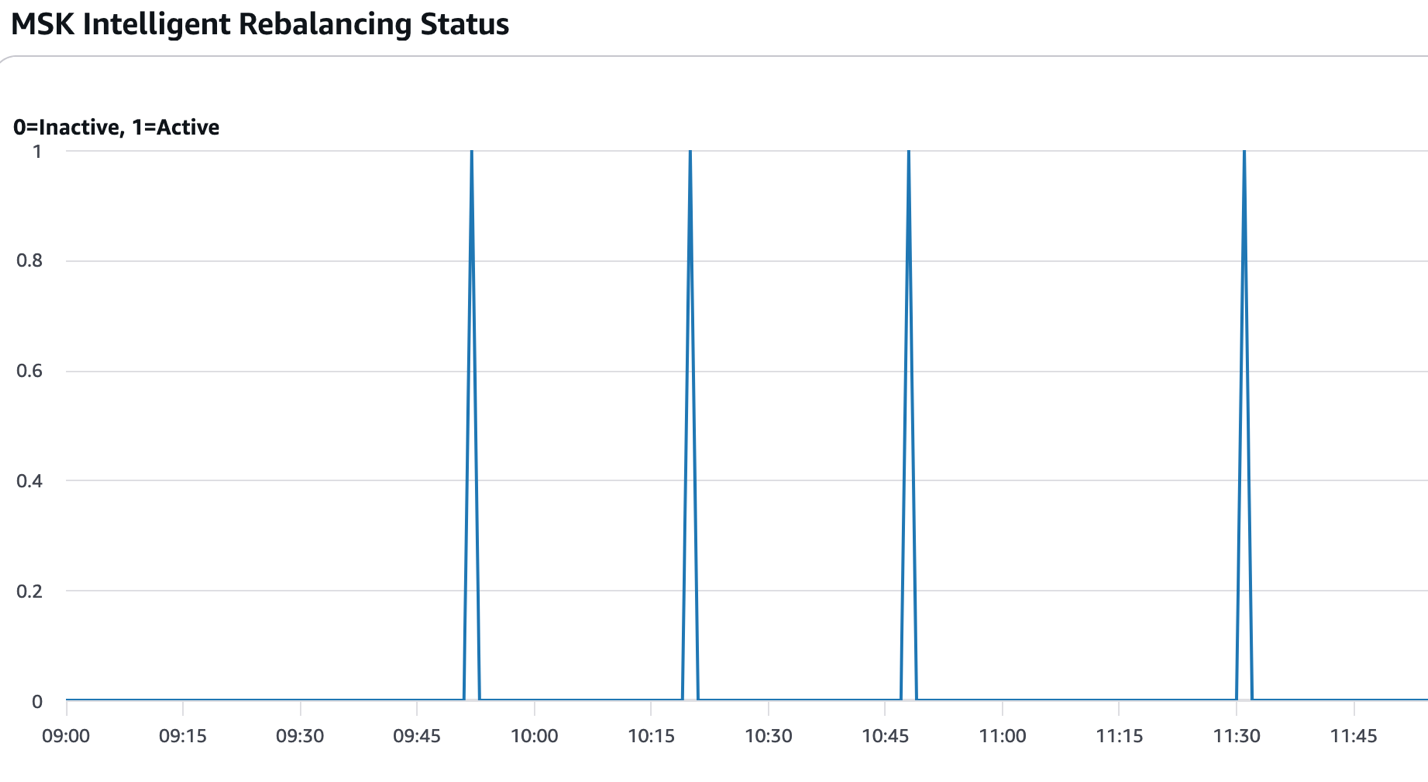
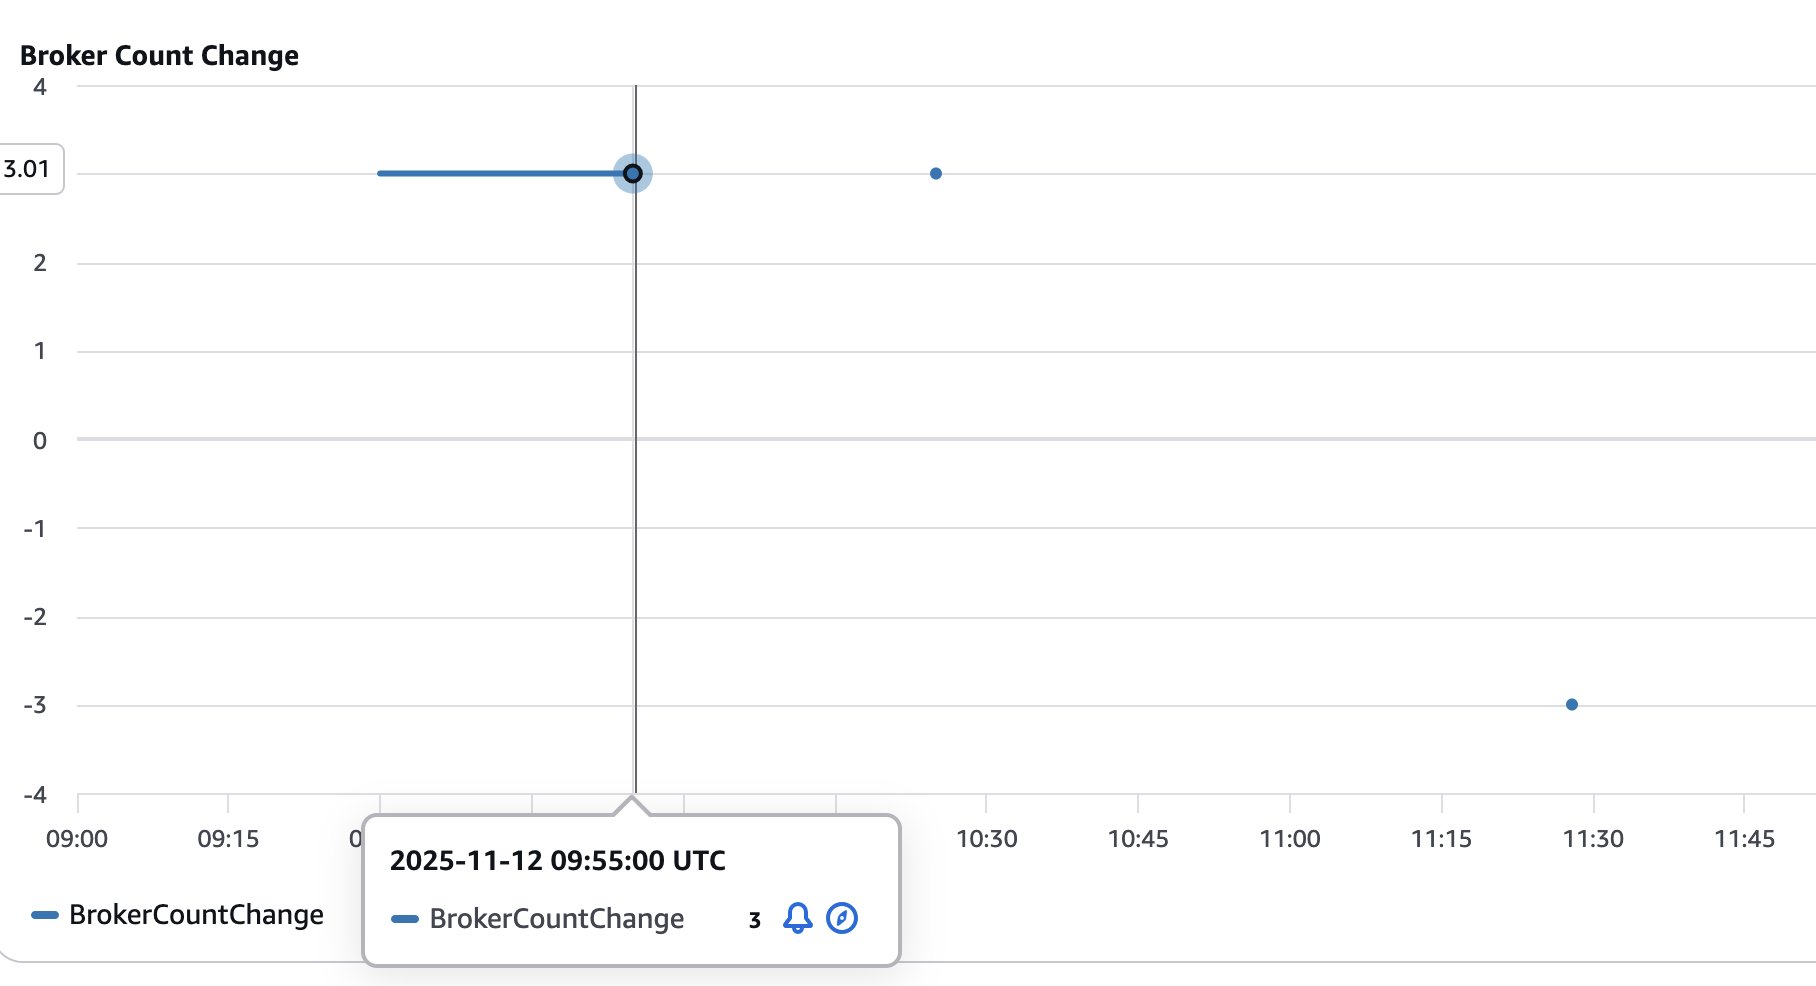
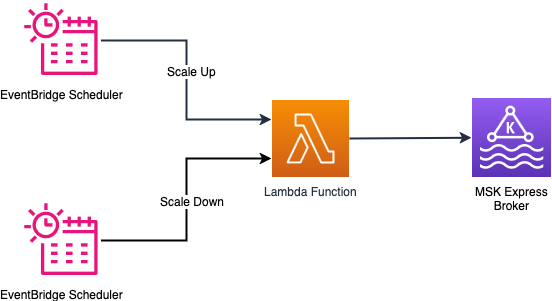
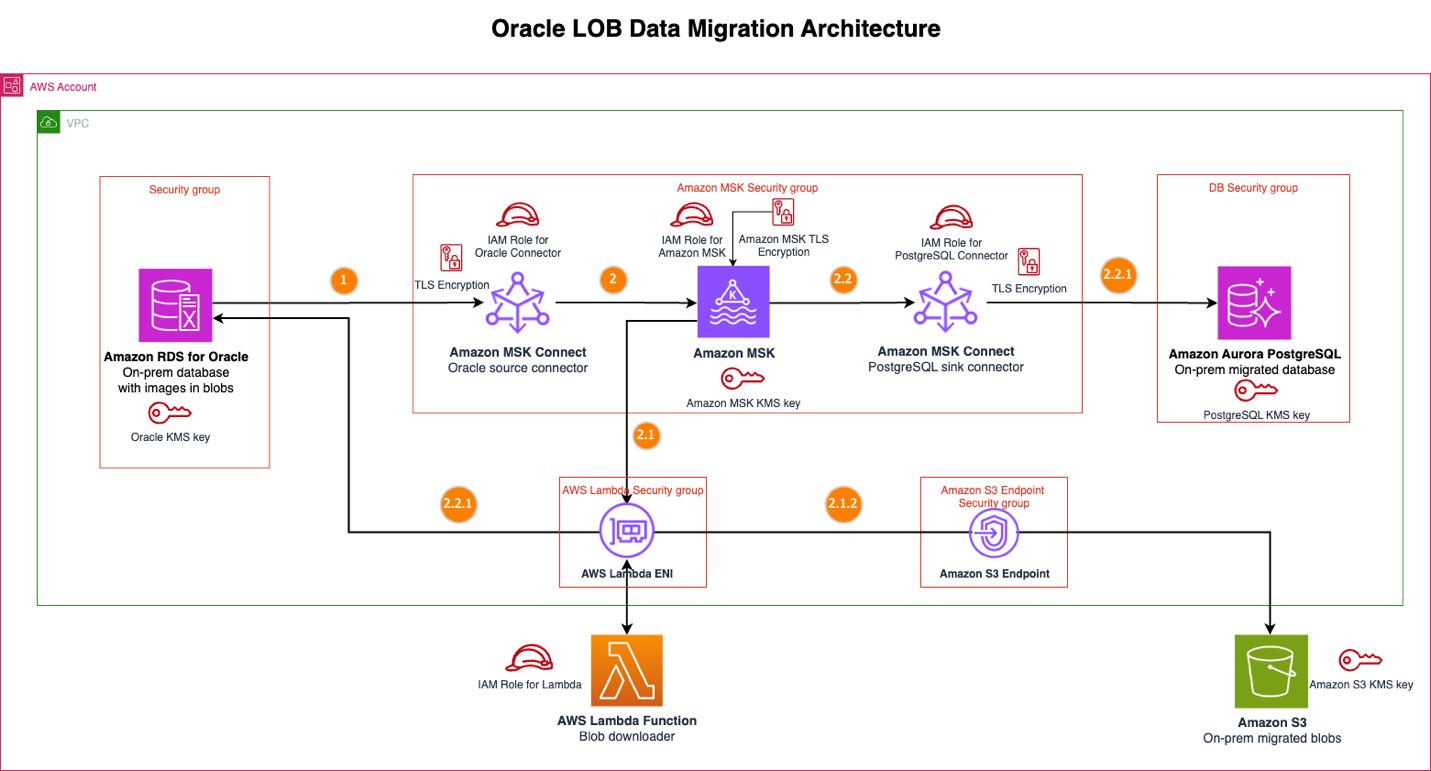
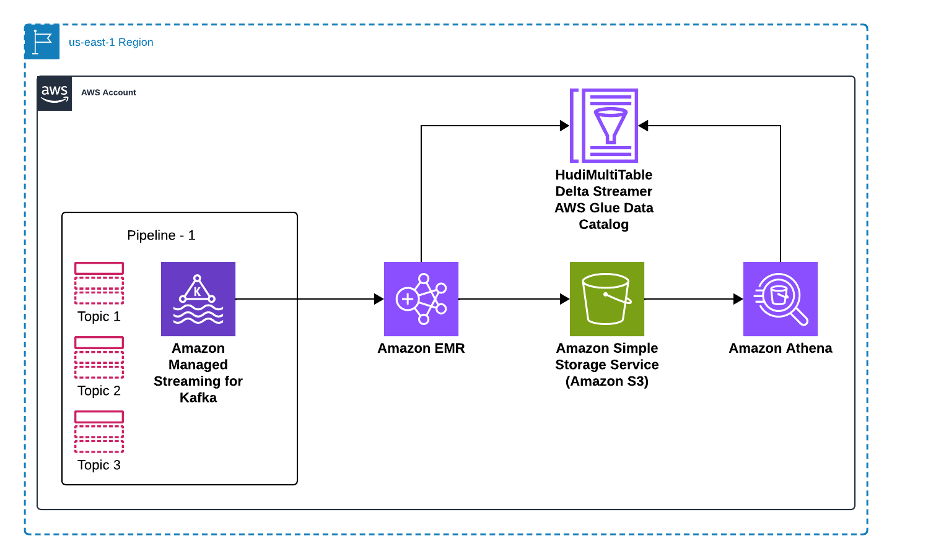
 Kalyan Janaki is Senior Big Data & Analytics Specialist with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS.
 Ankit Mishra is a Senior Solutions Architect at Amazon Web Services, where he supports healthcare and life sciences customers around the globe. He is passionate about helping organizations design and build secure, scalable, reliable, and cost-effective cloud solutions. Outside of work, Ankit enjoys
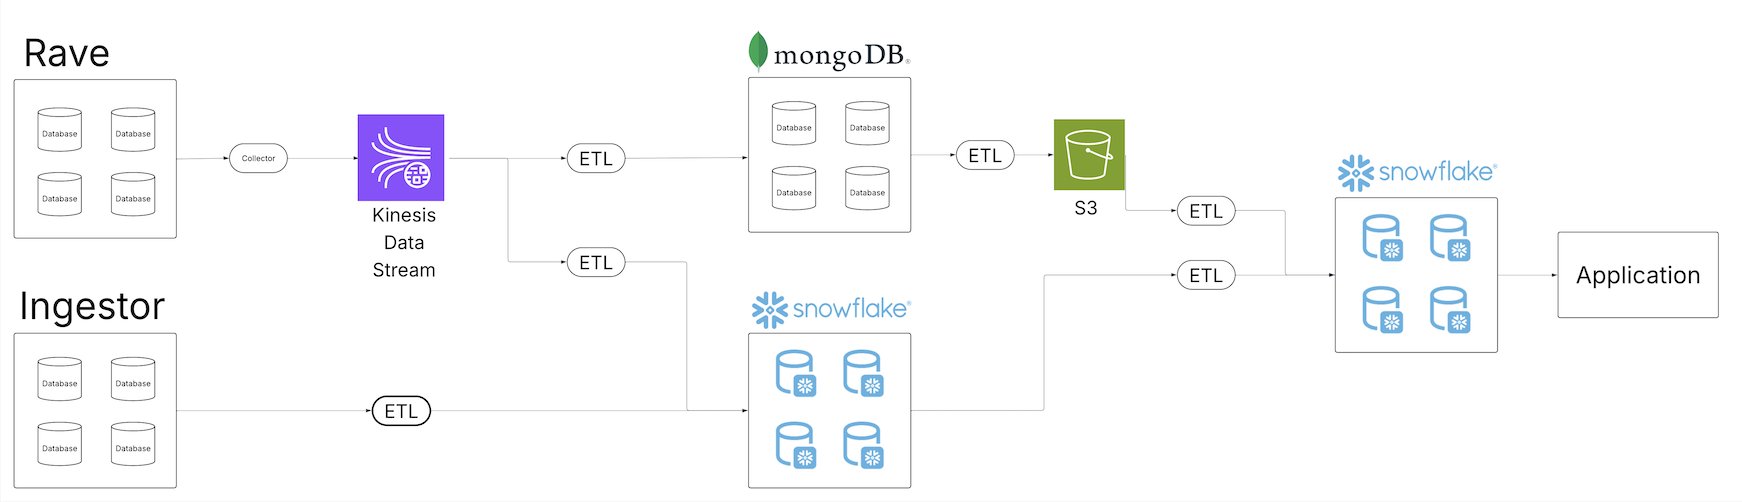
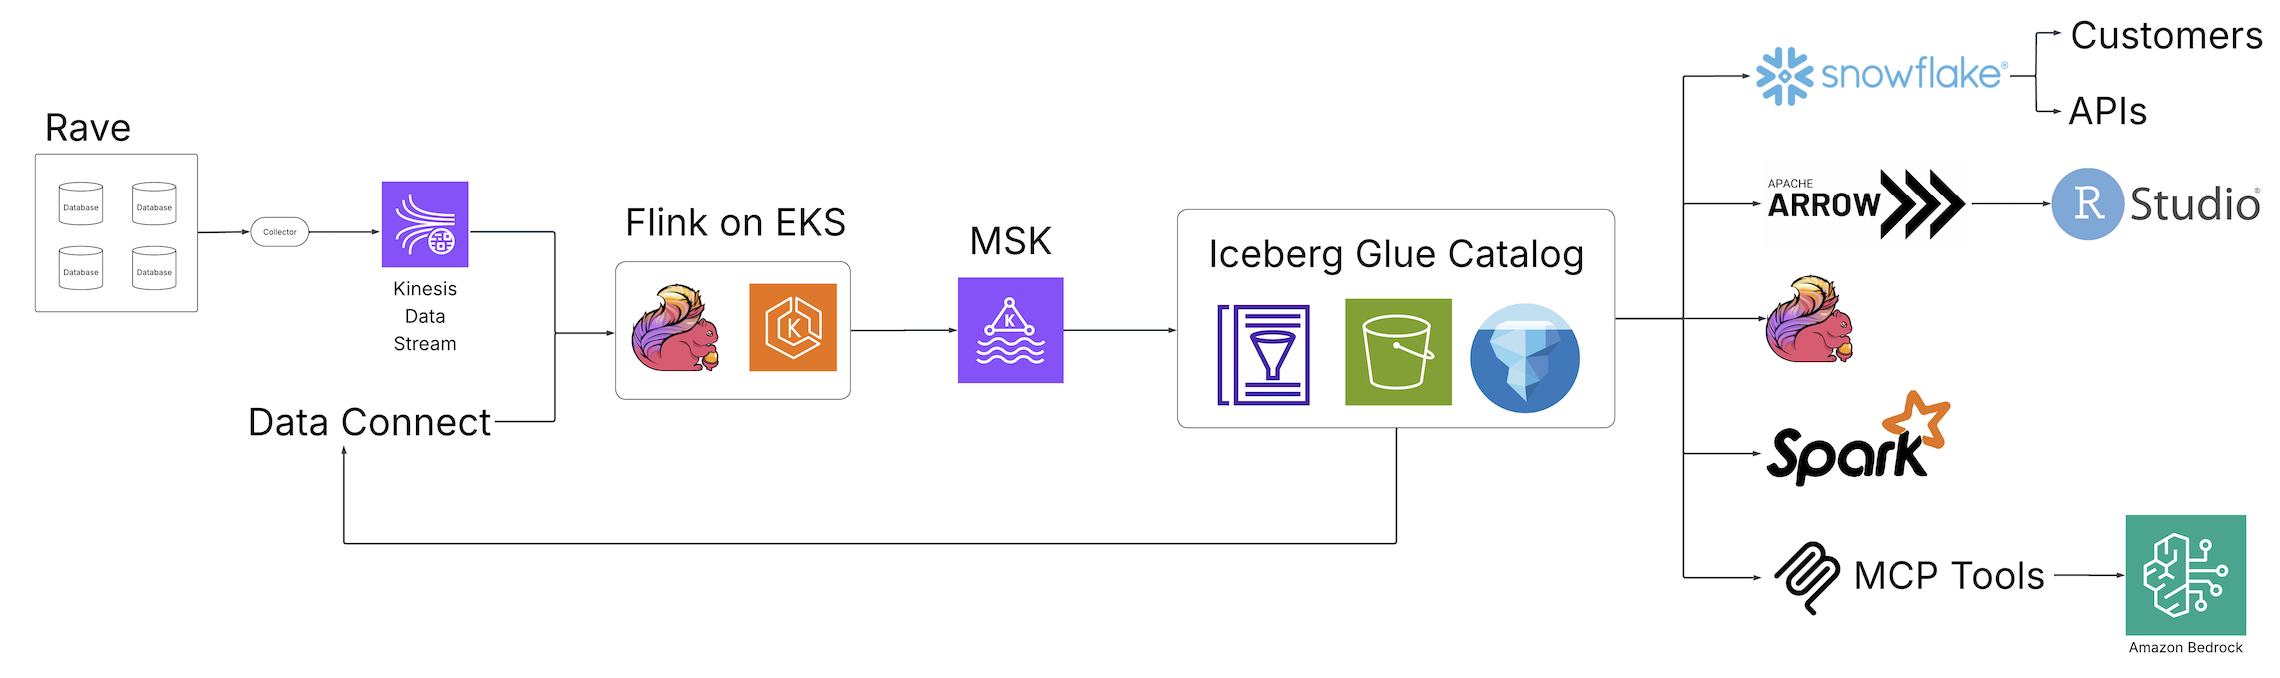
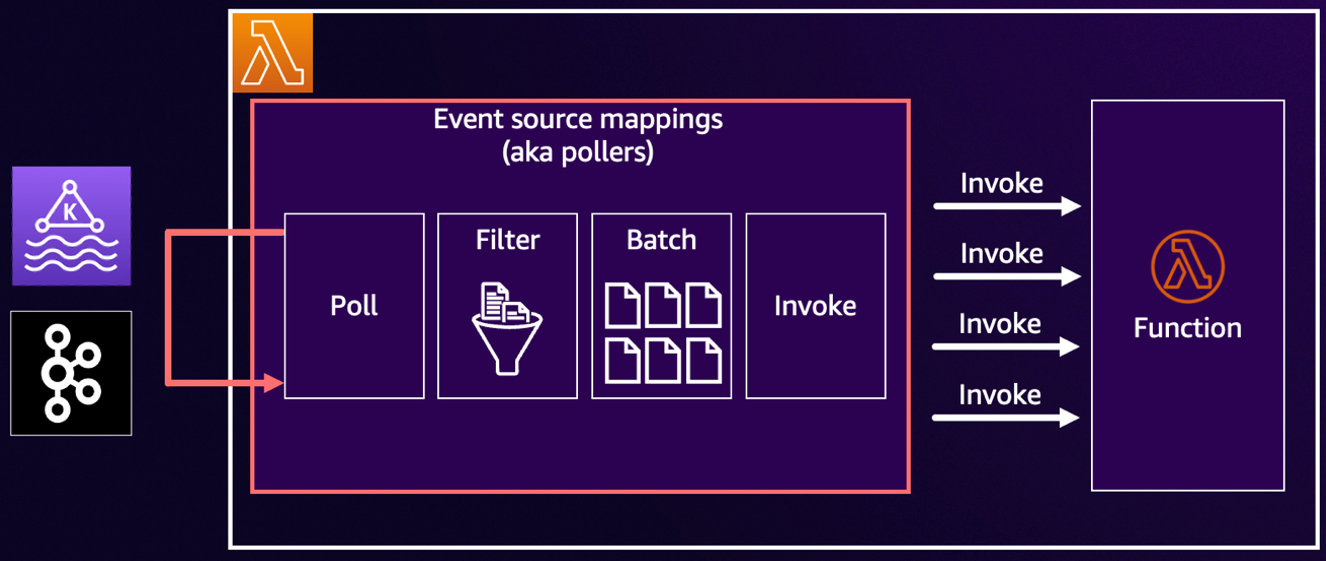
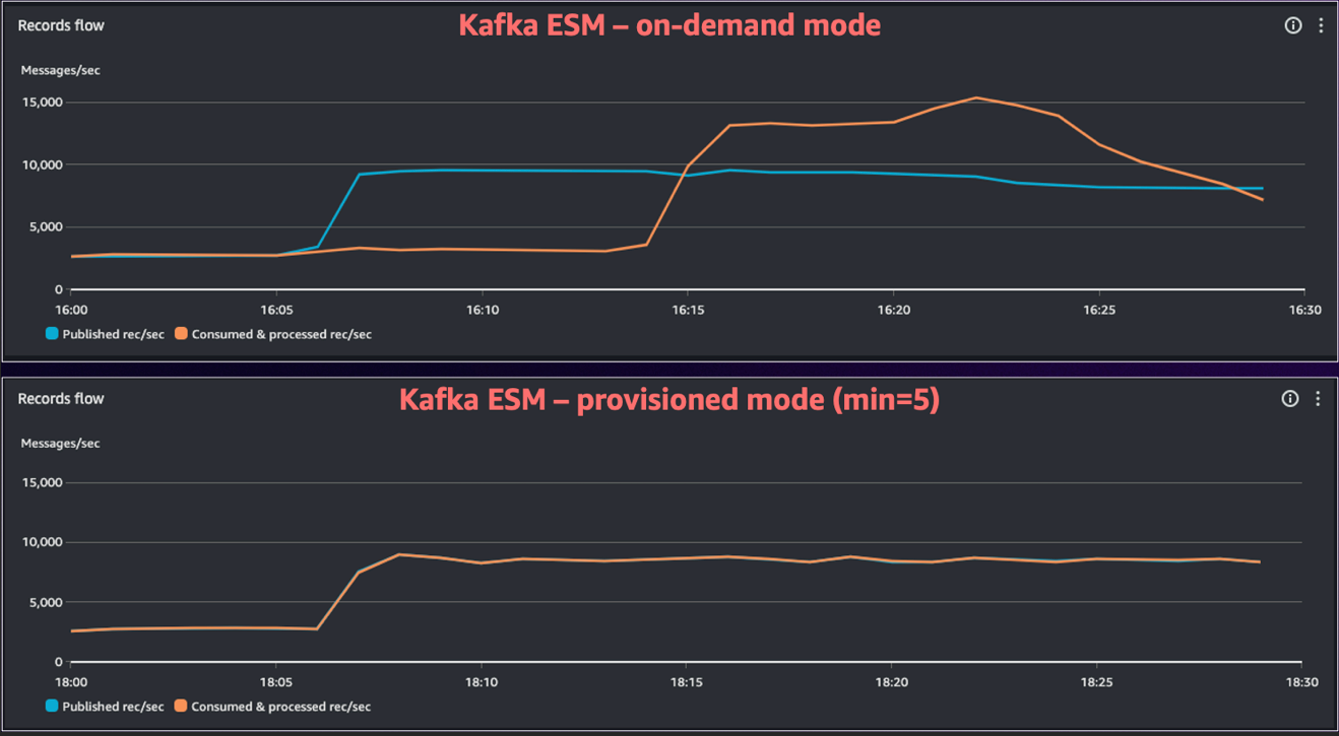
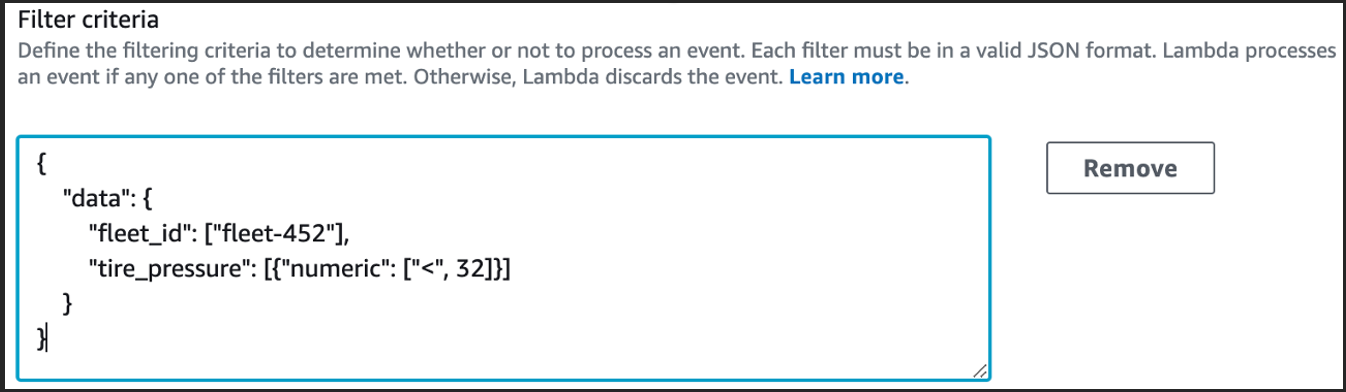
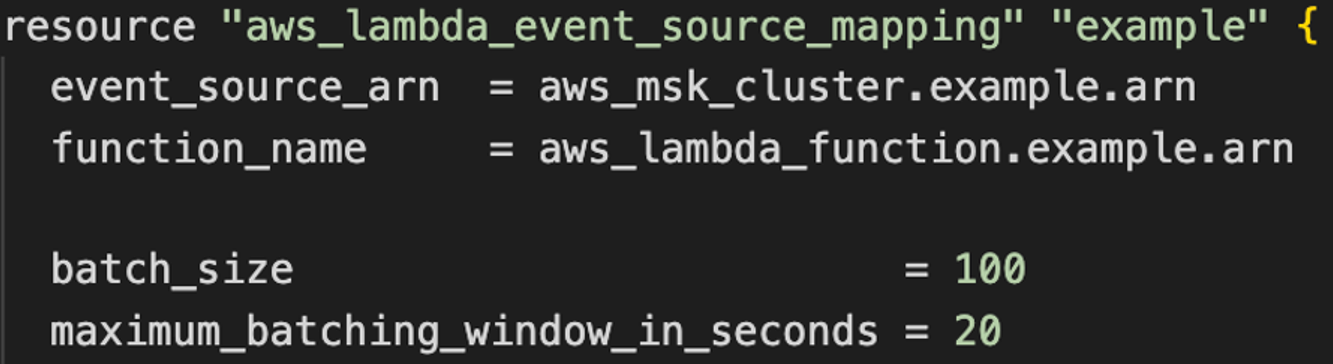
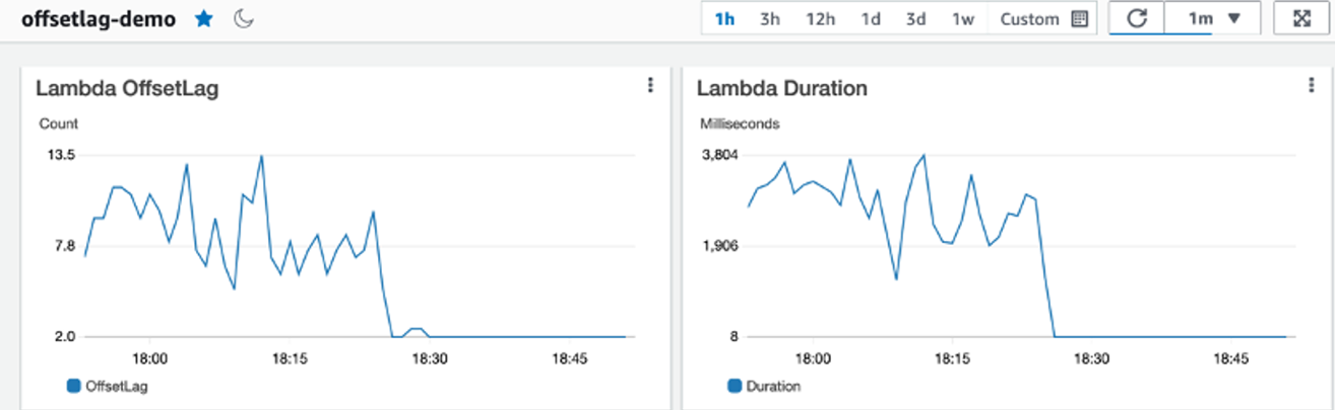
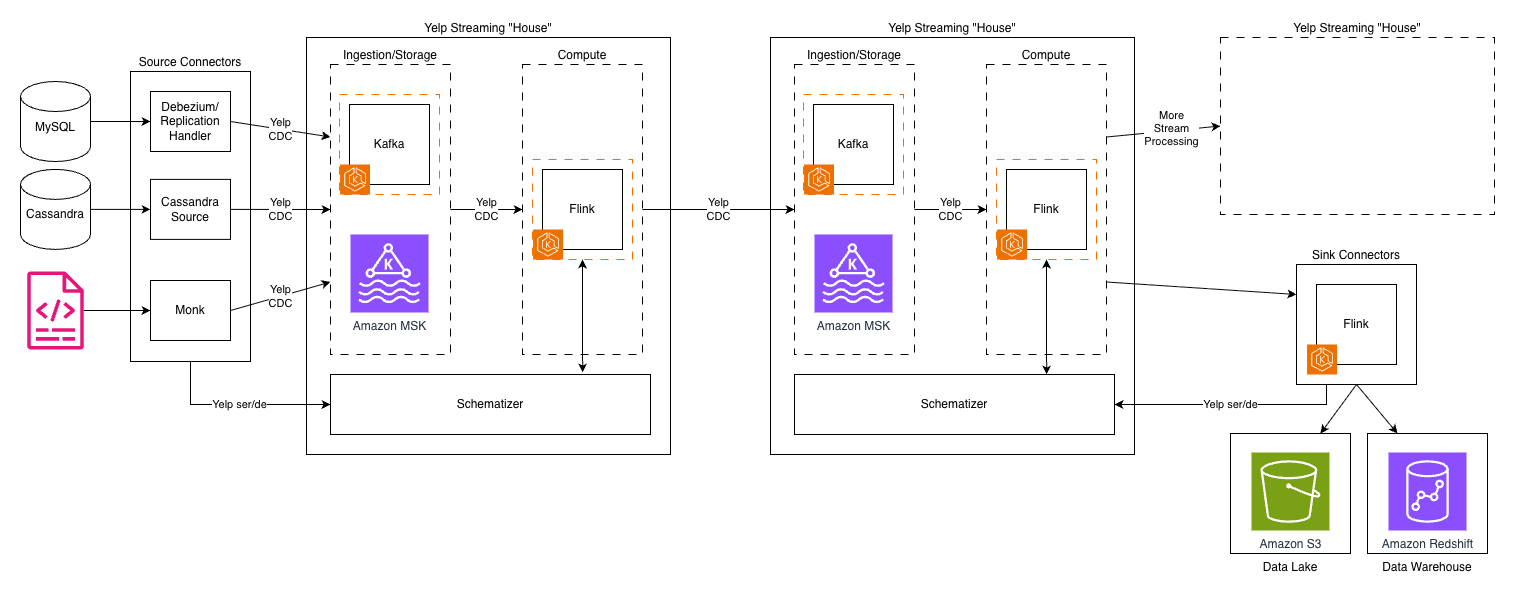
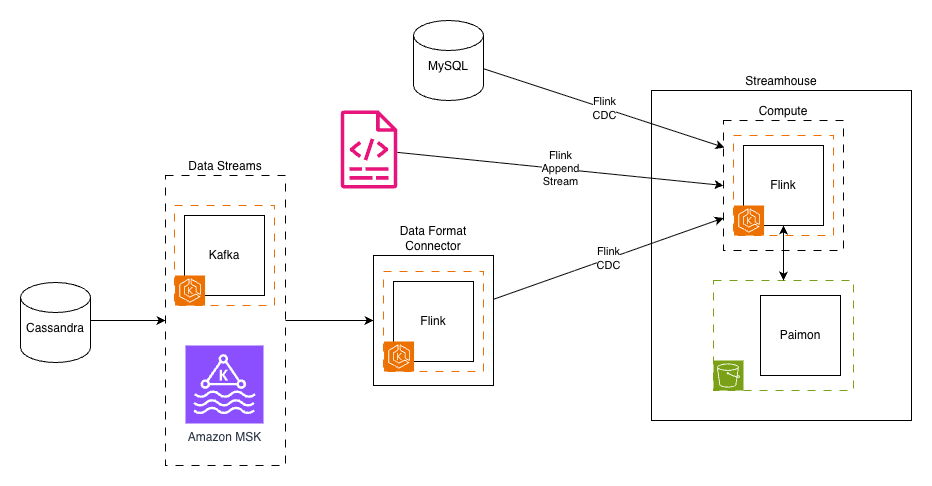
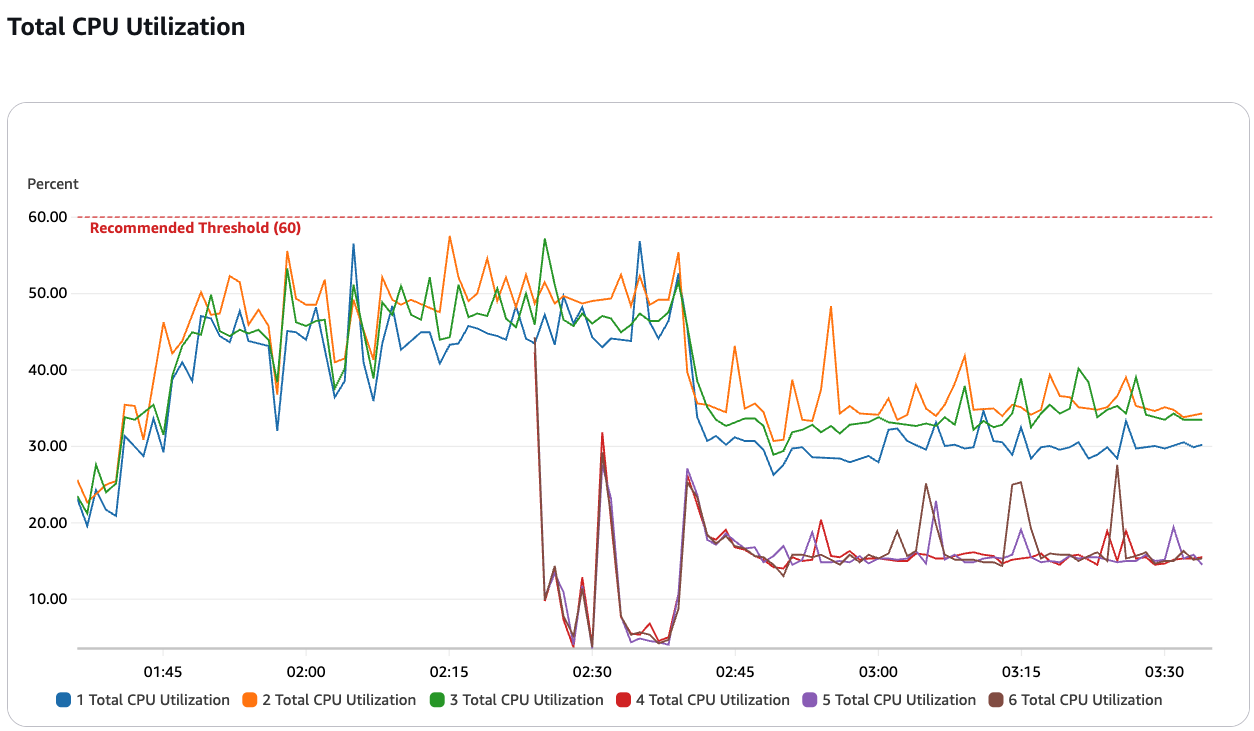
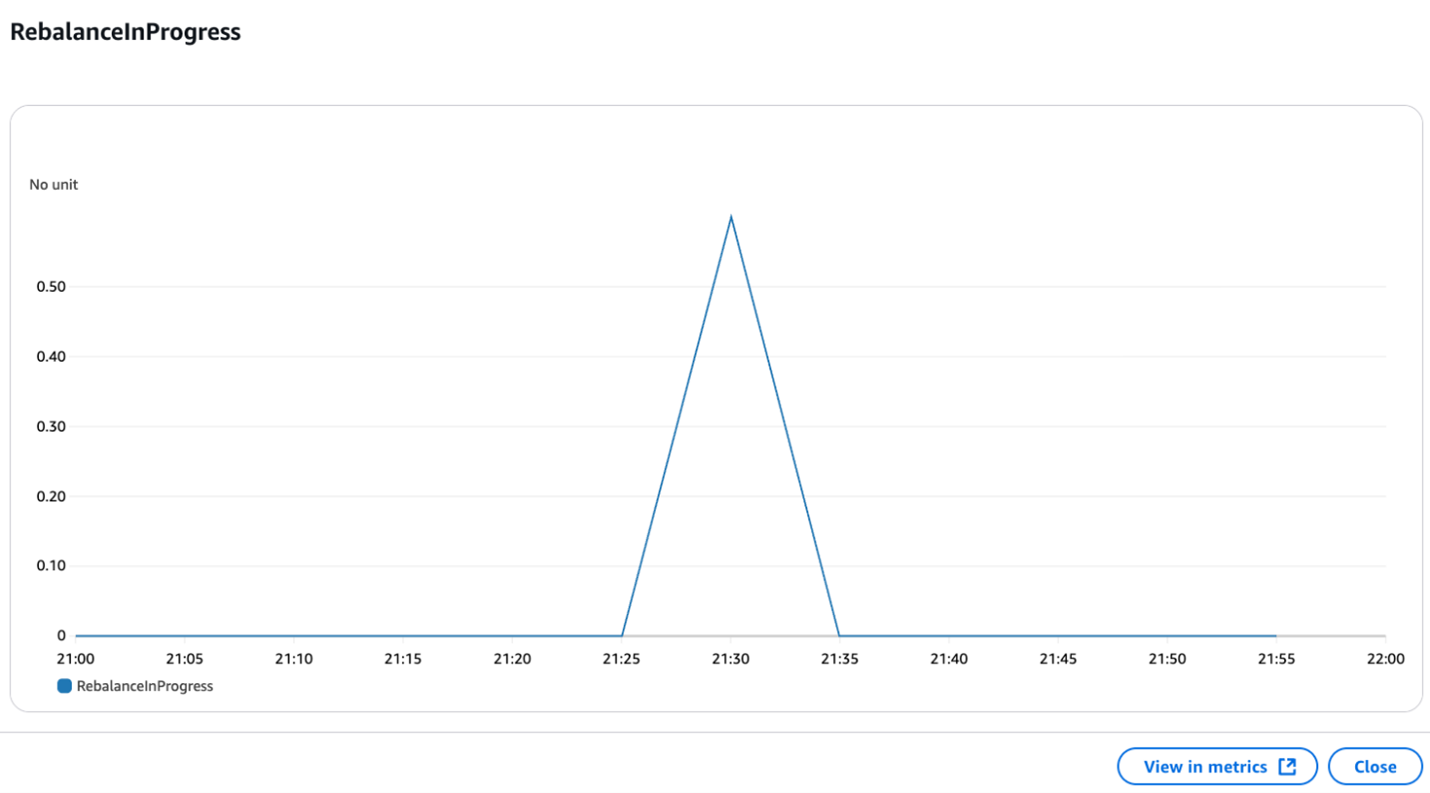
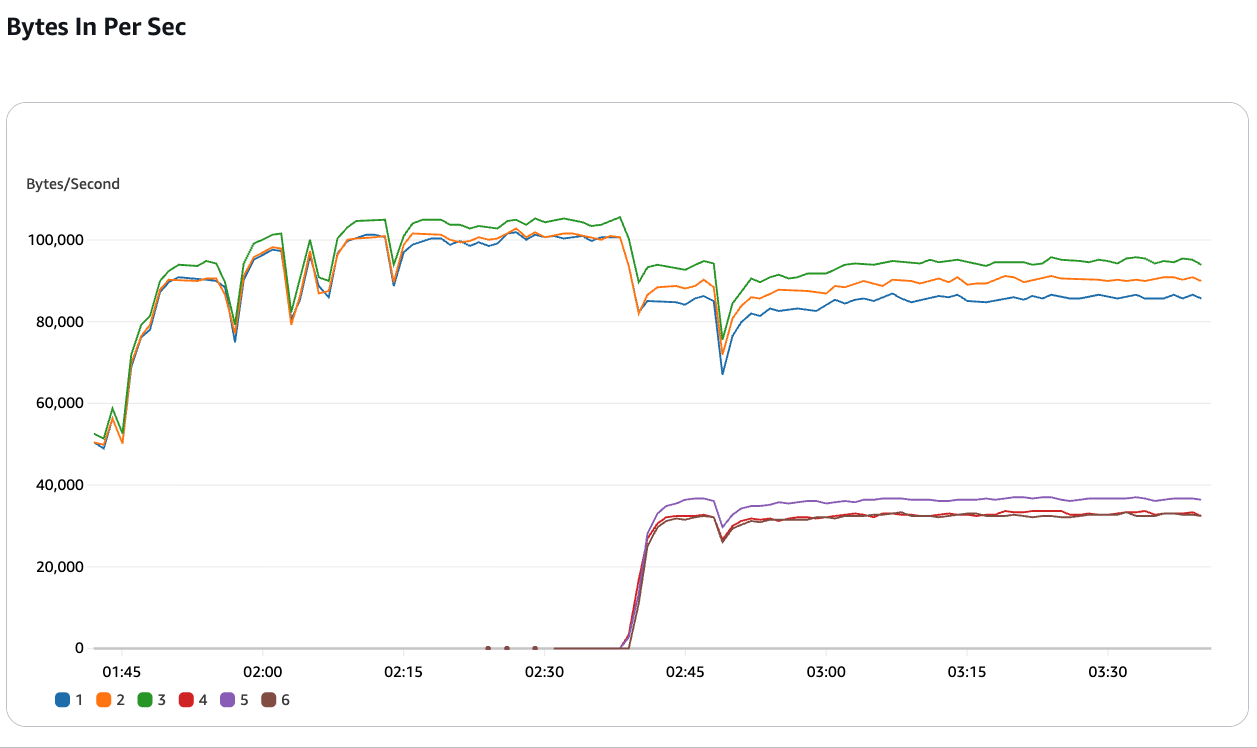
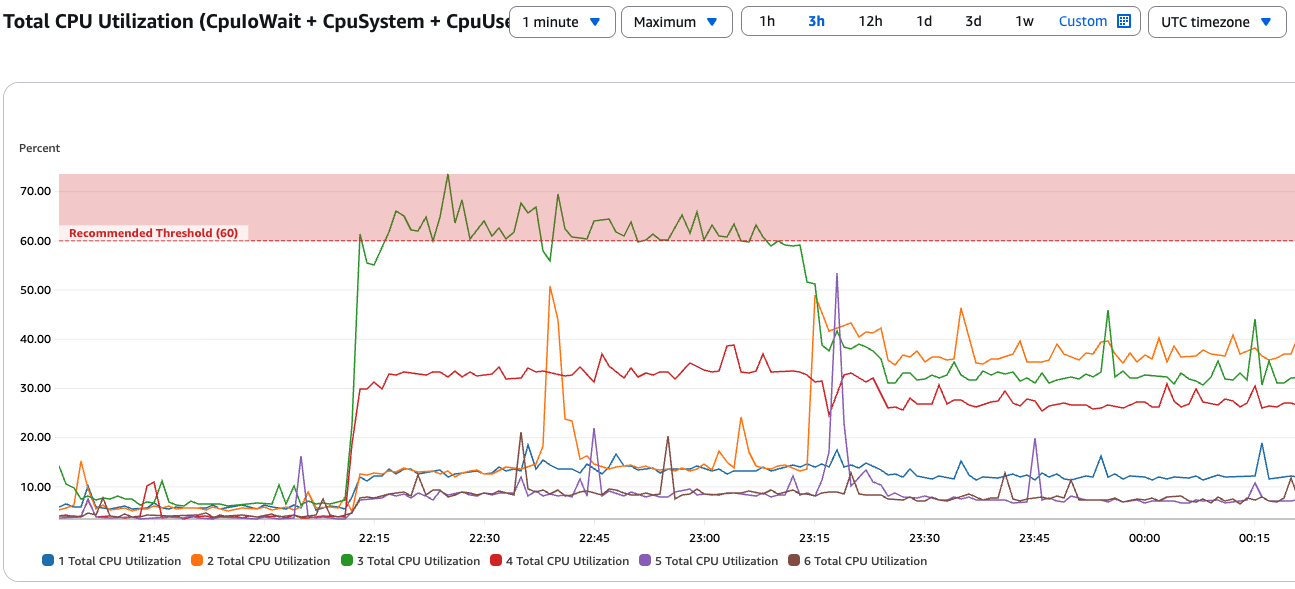

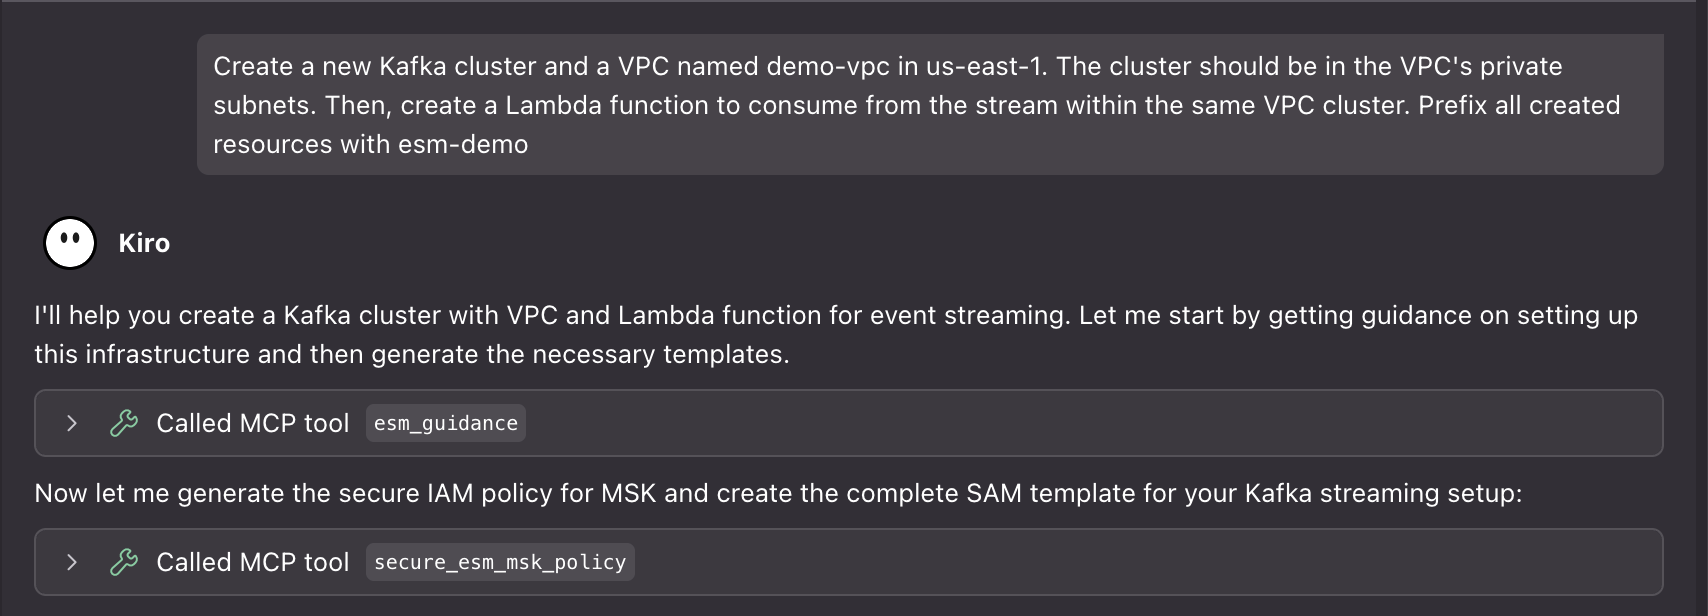
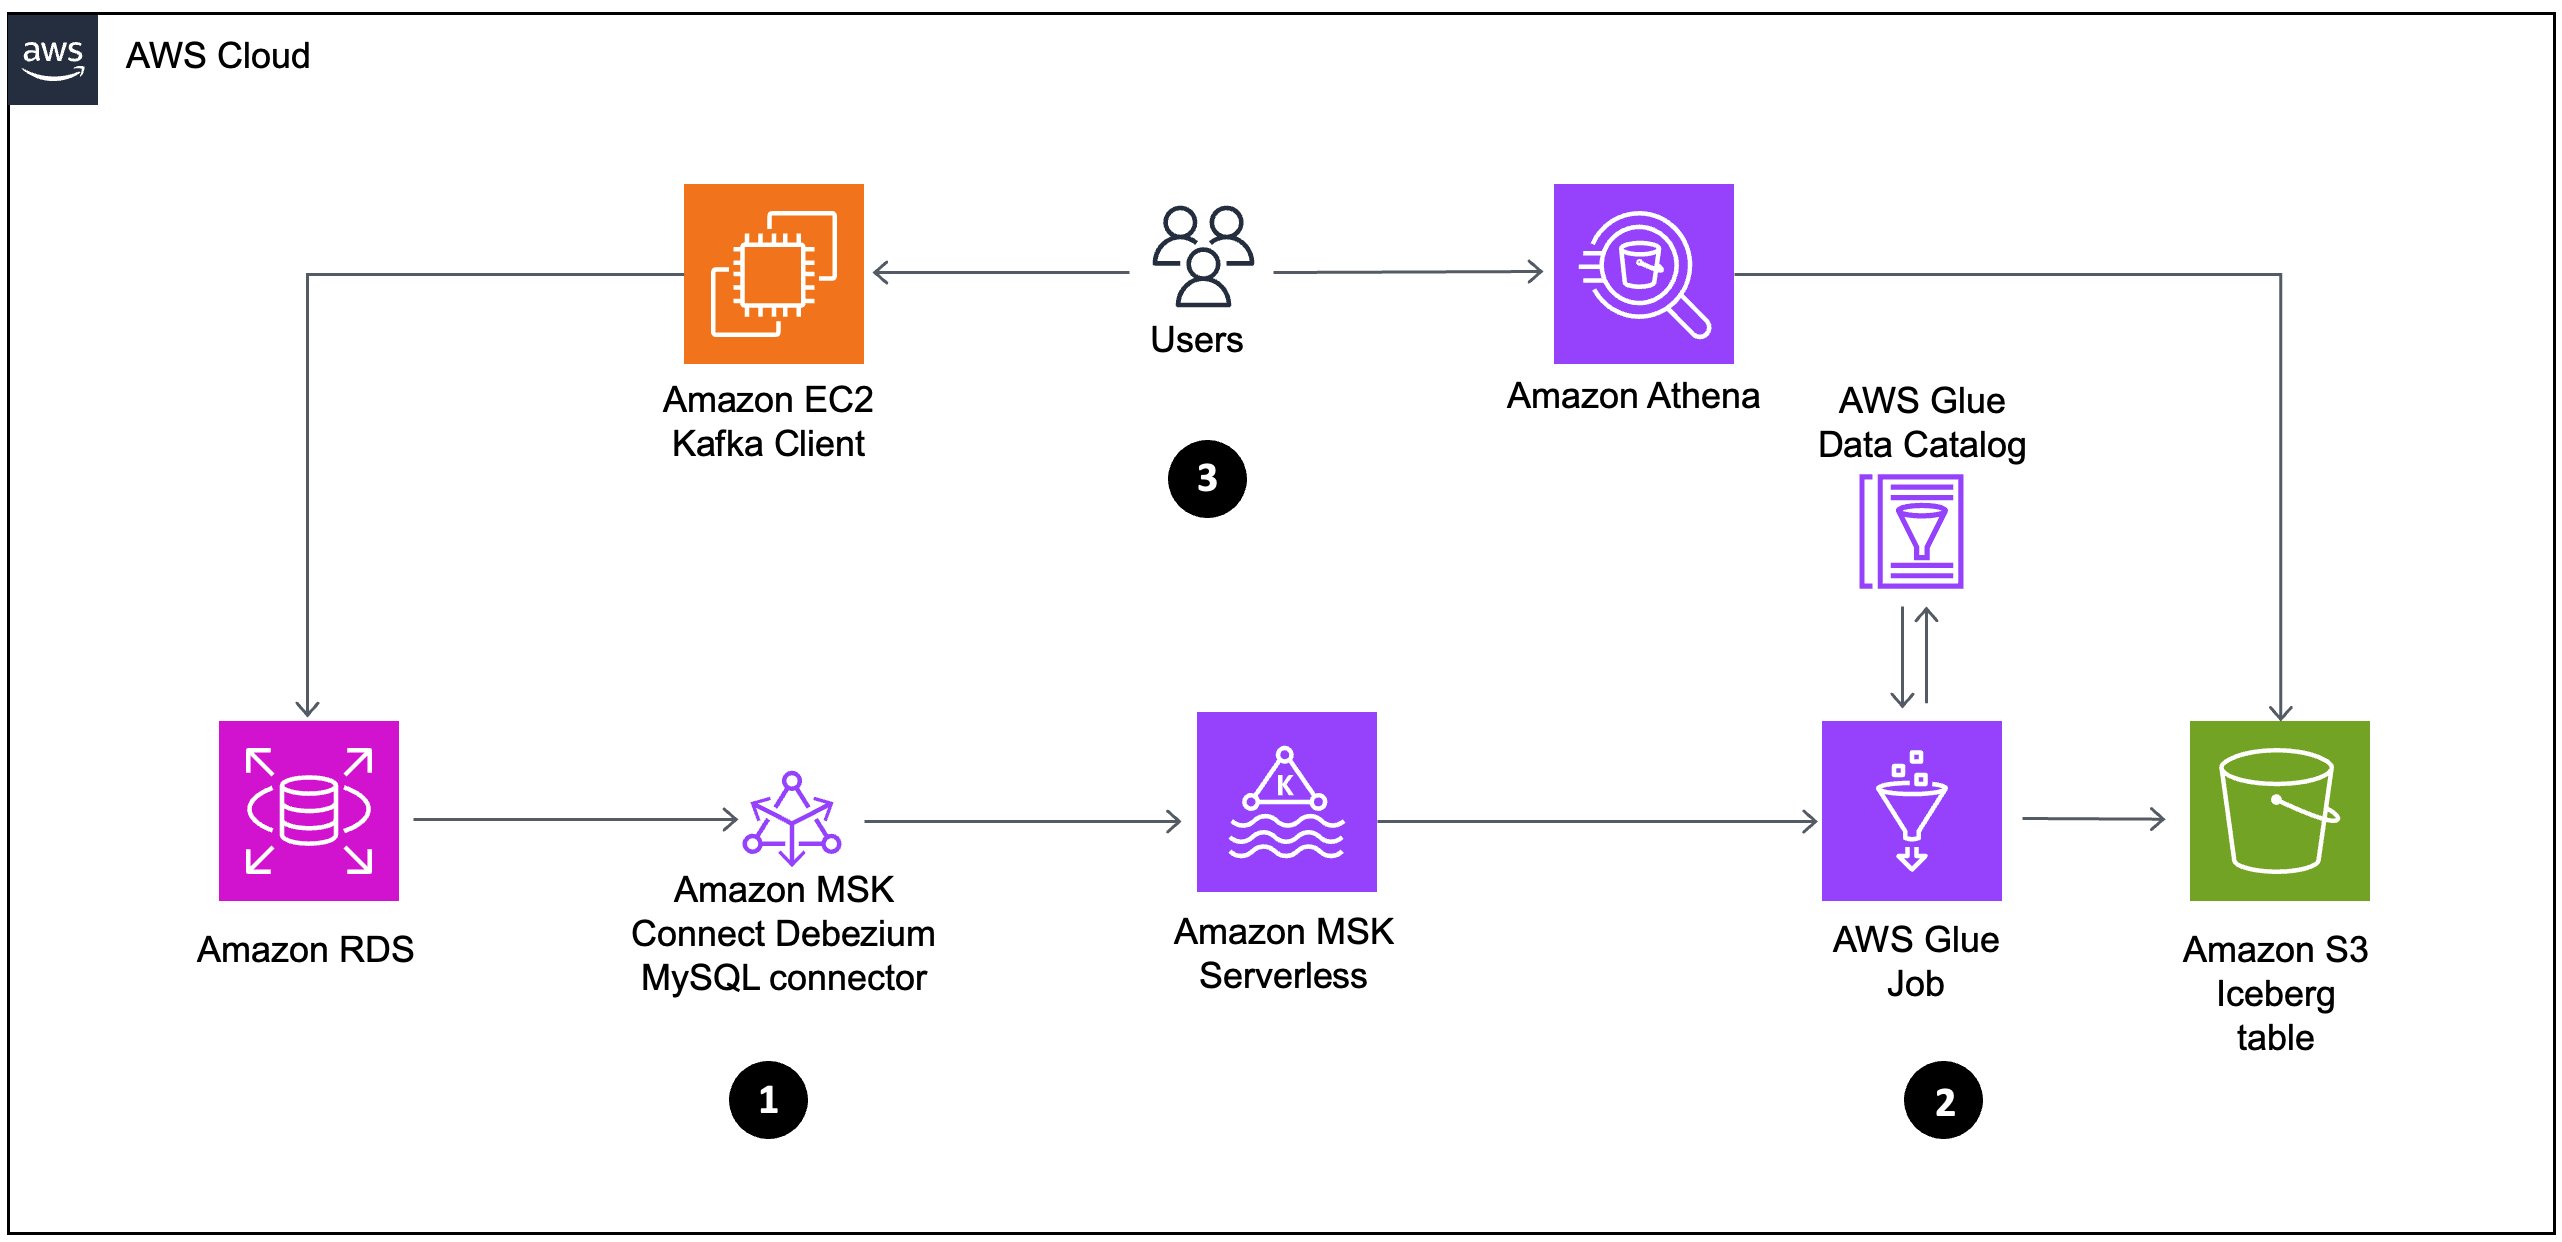
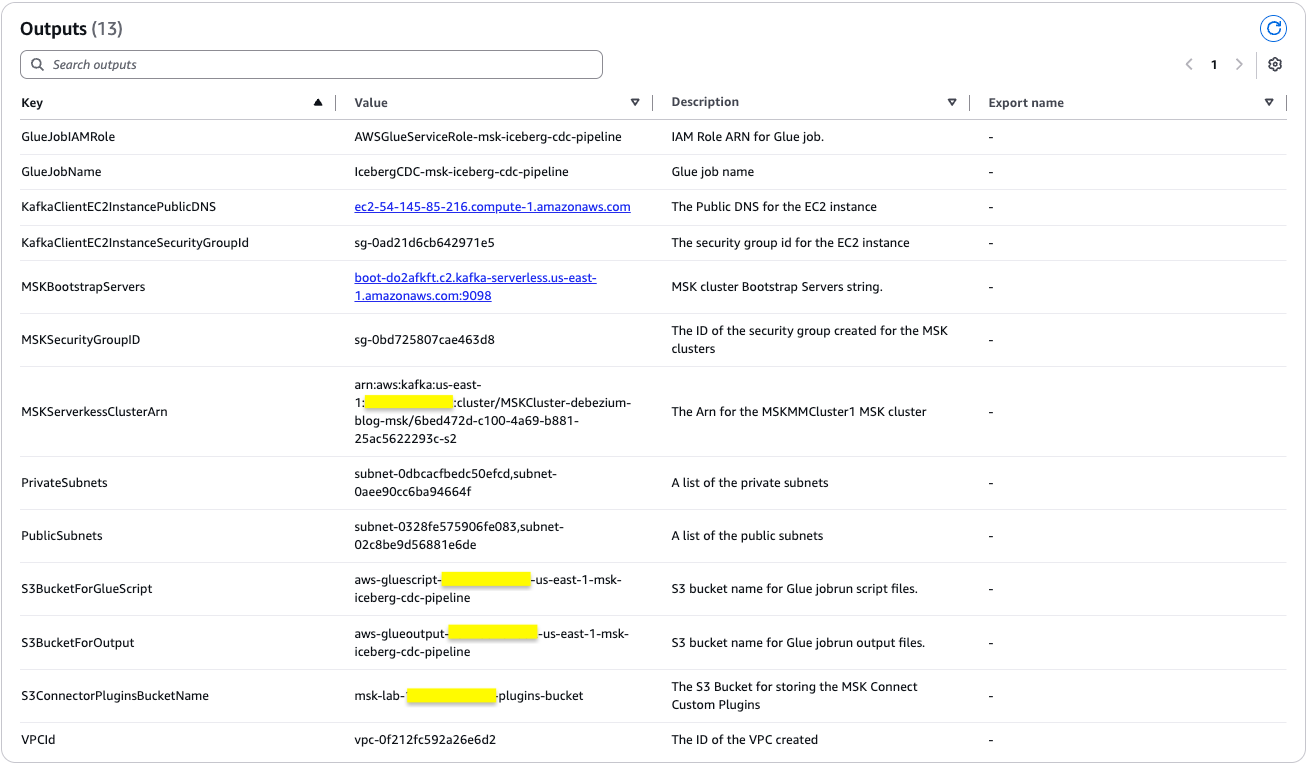
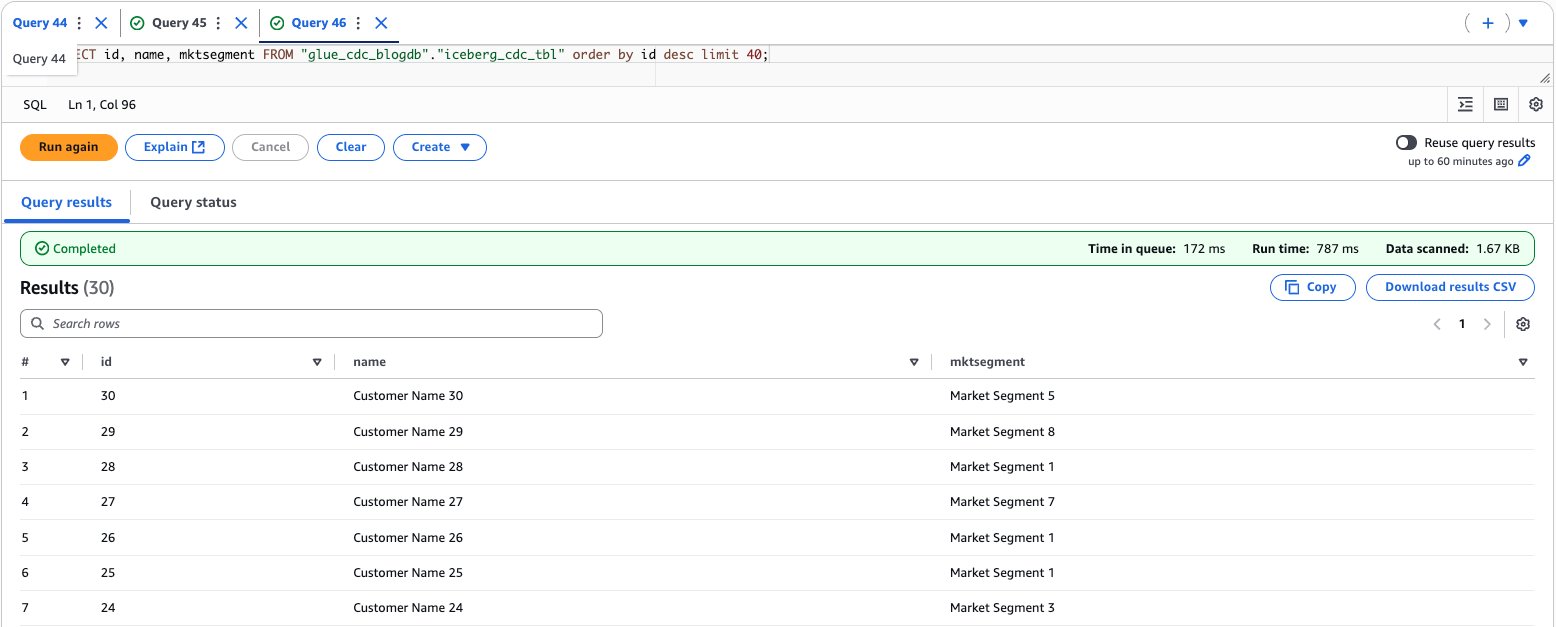
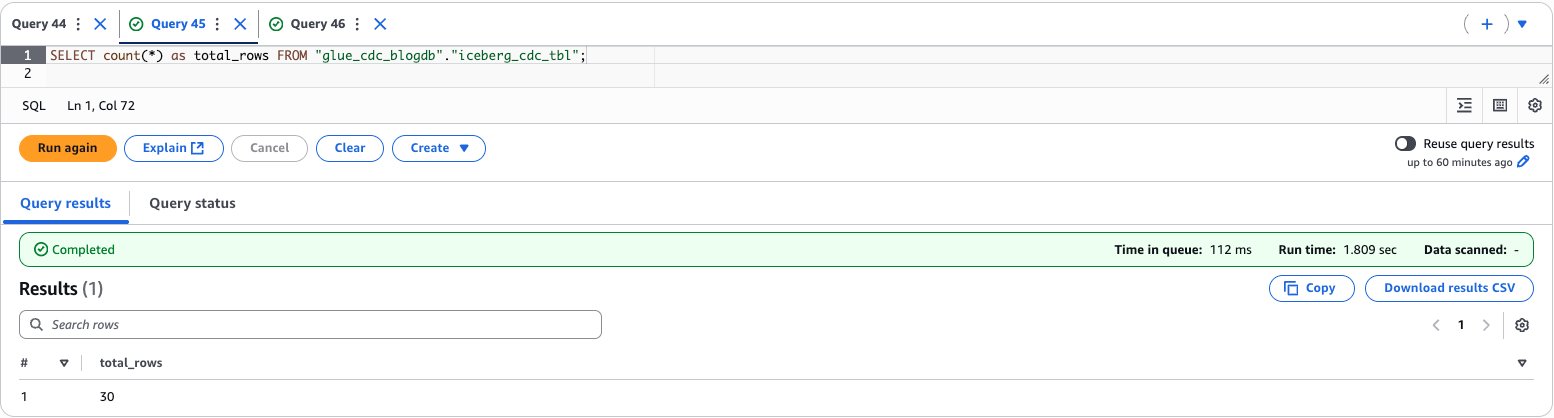

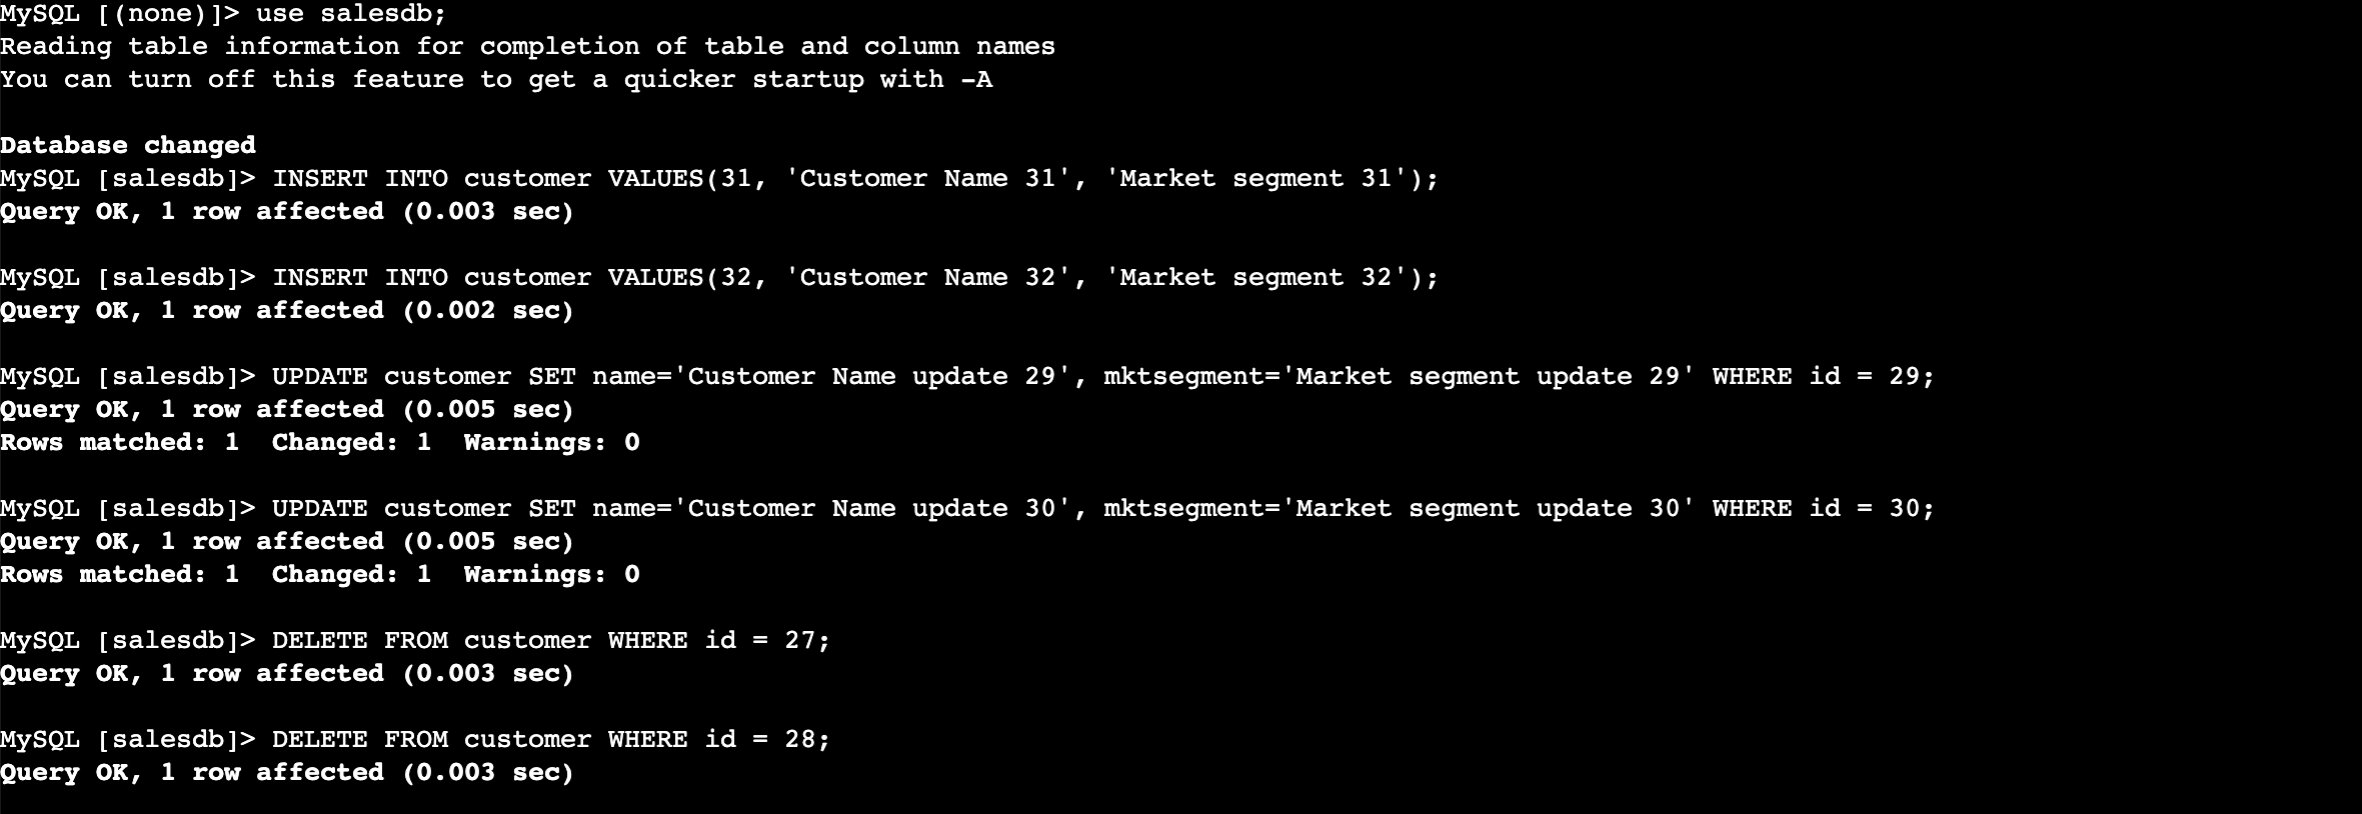
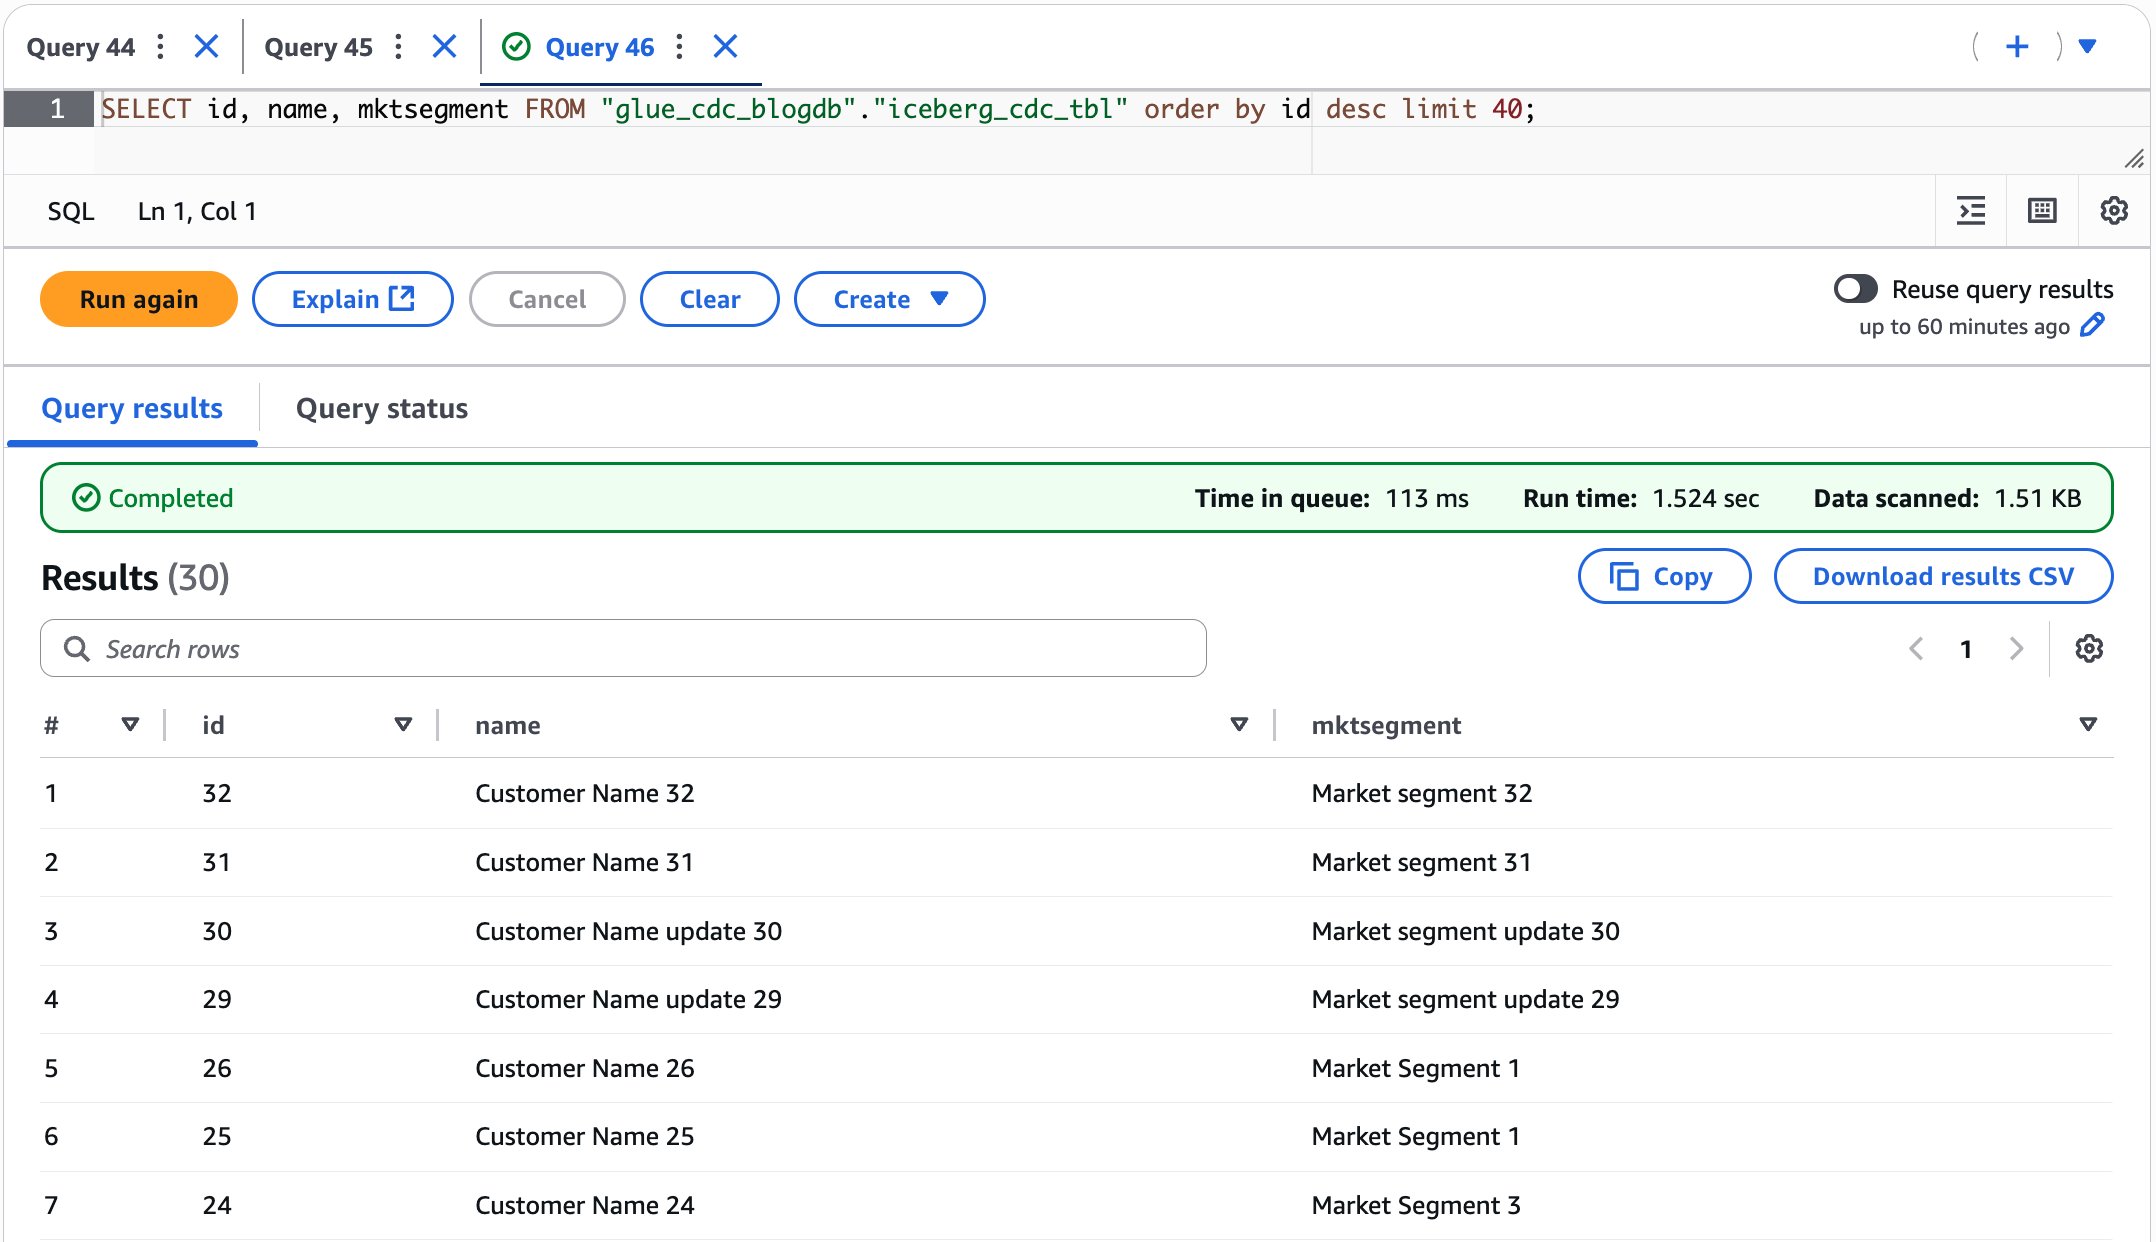
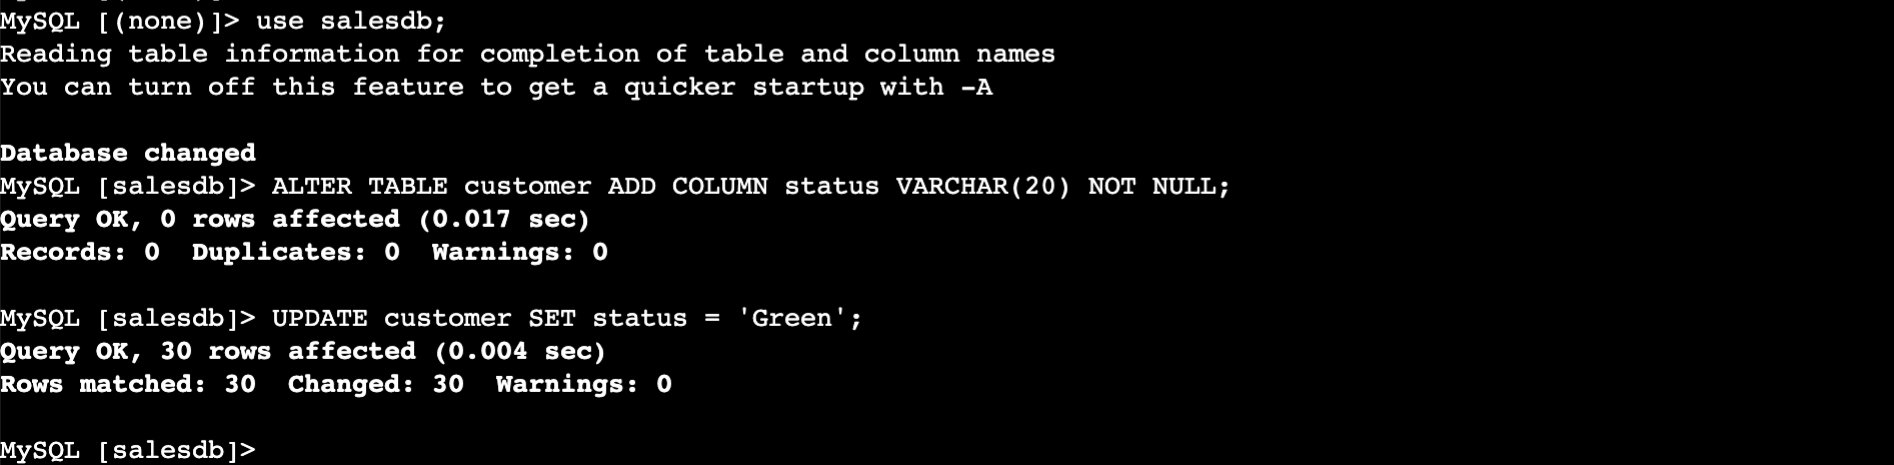
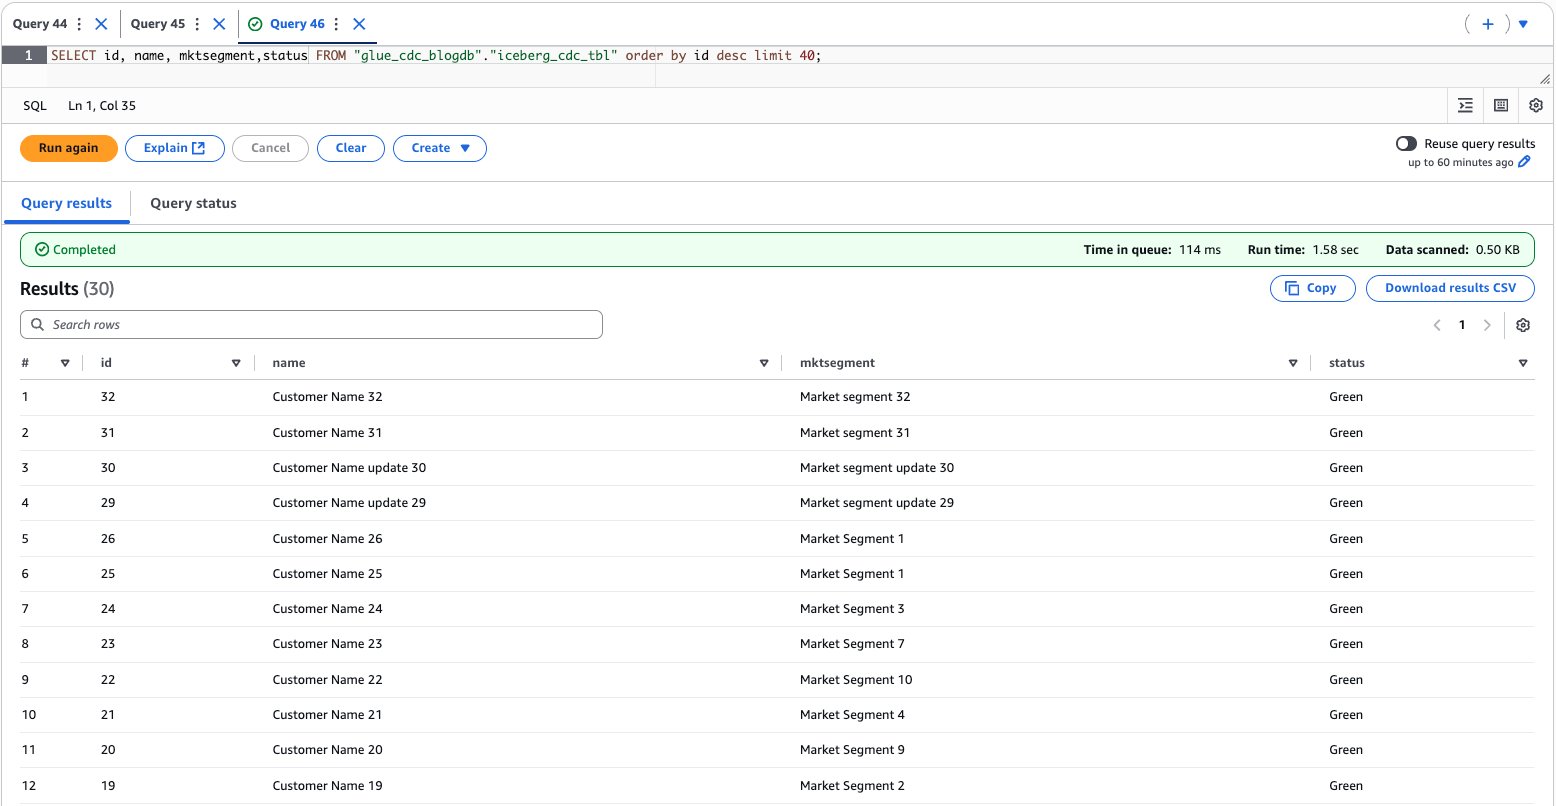
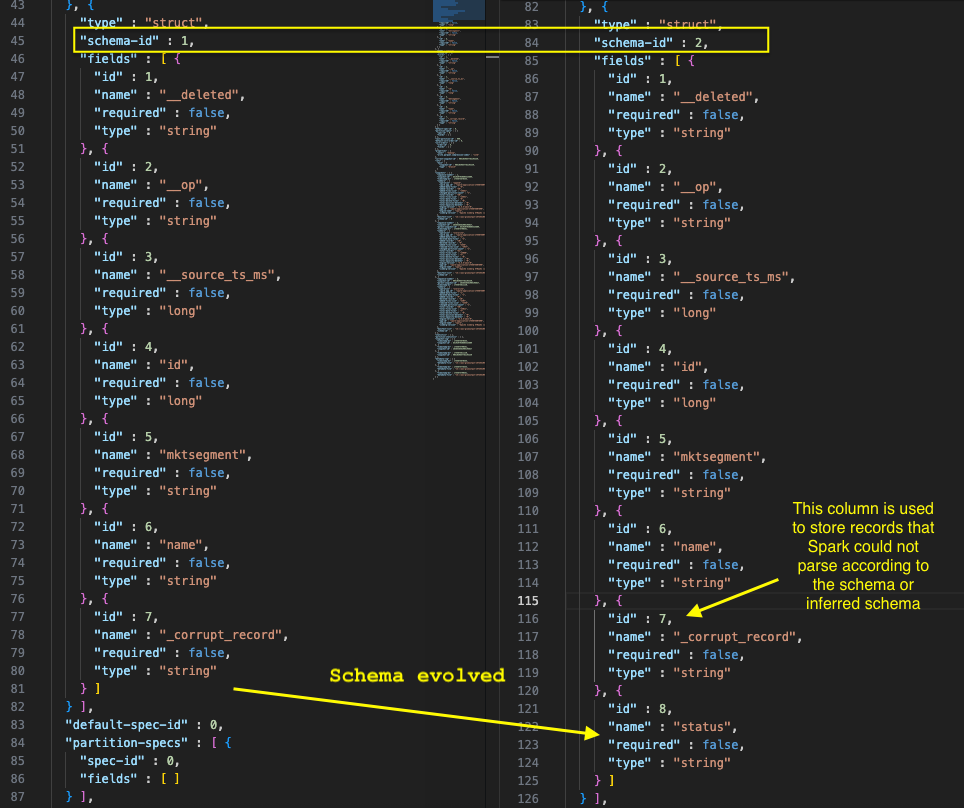
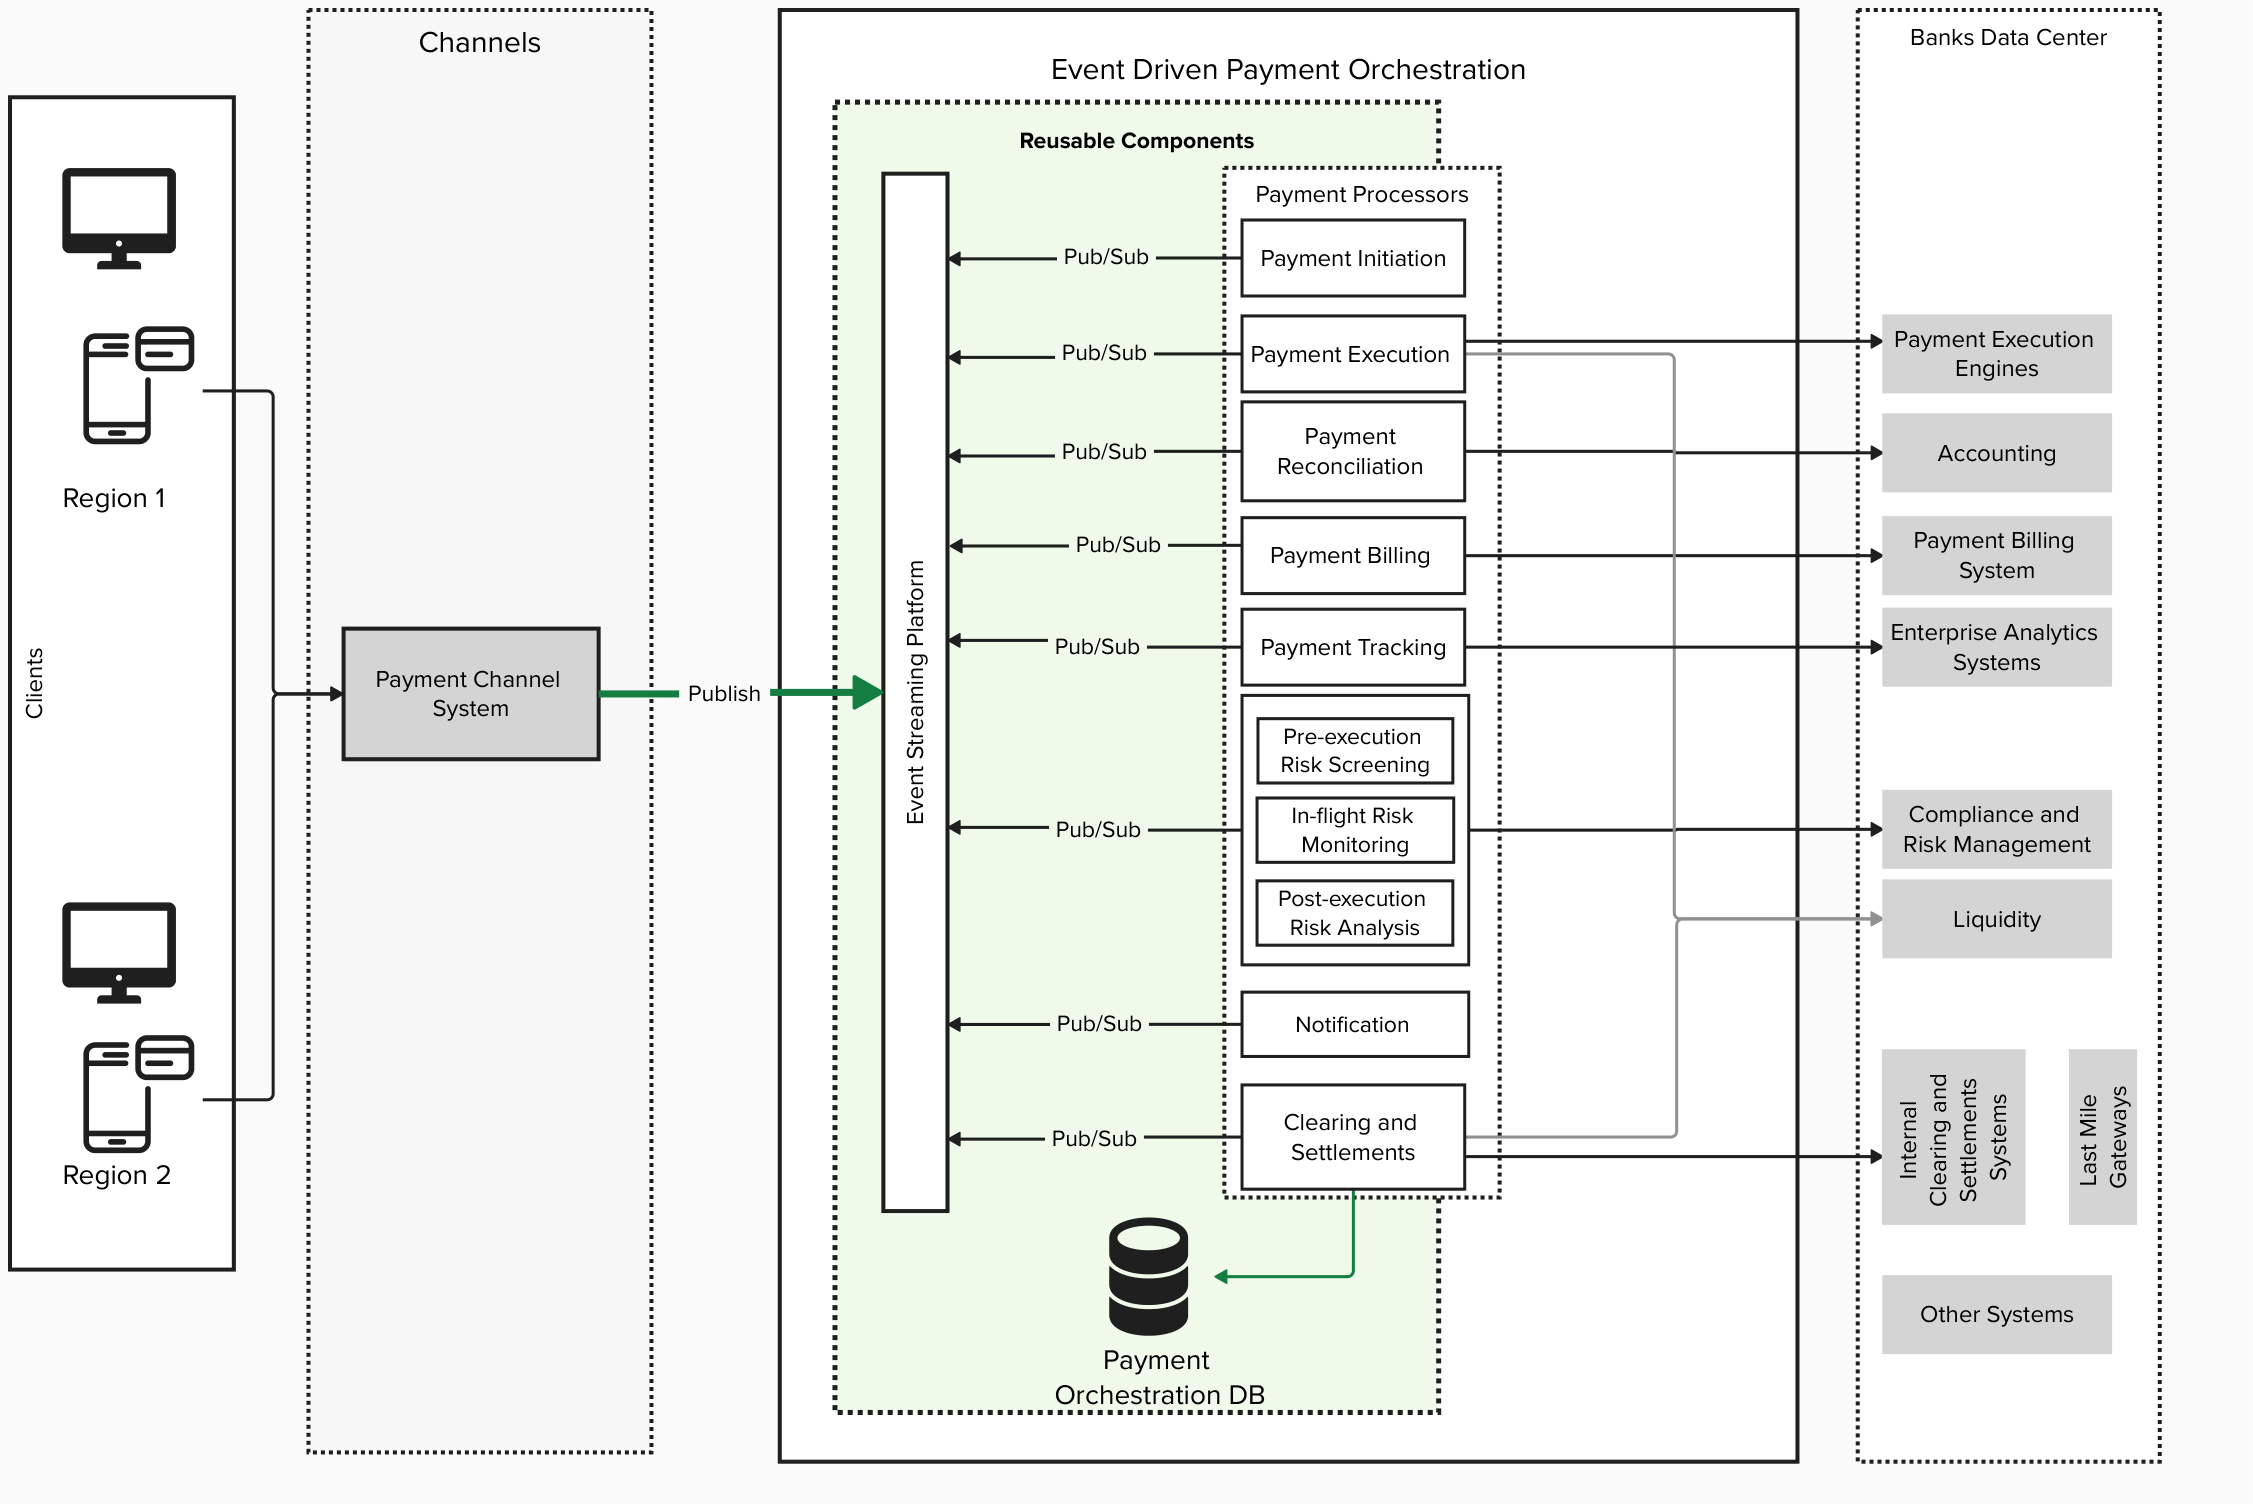
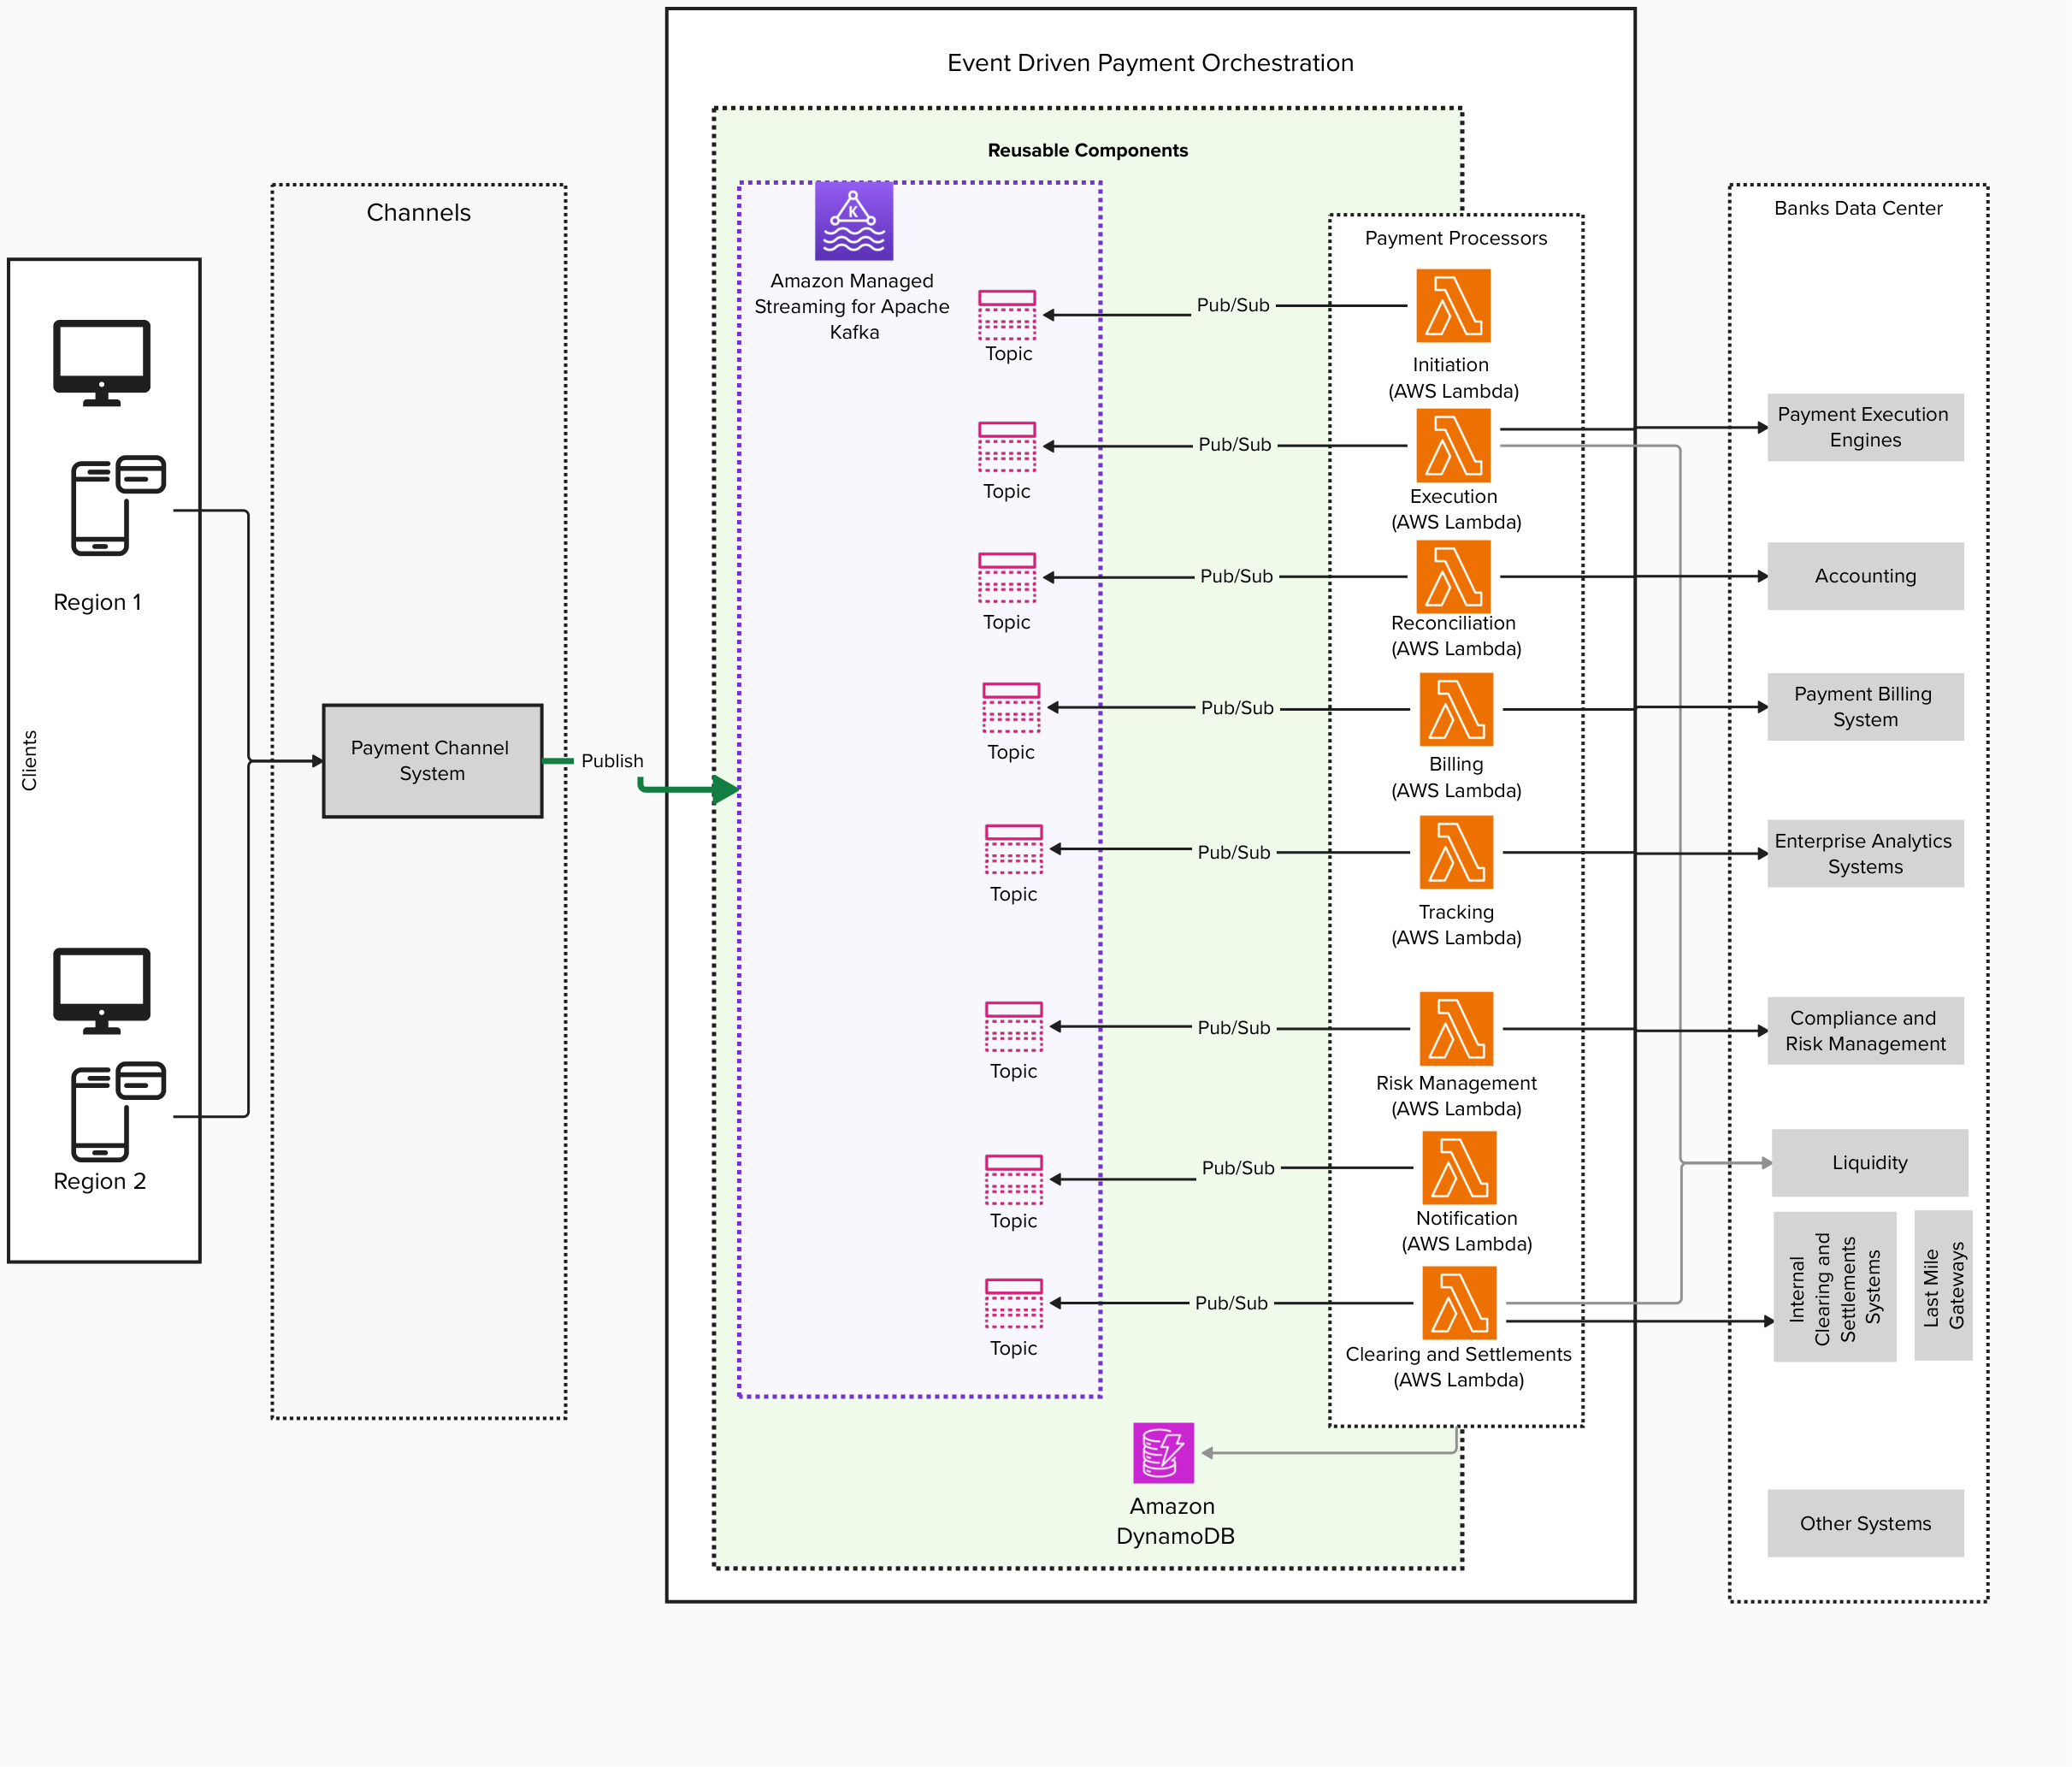
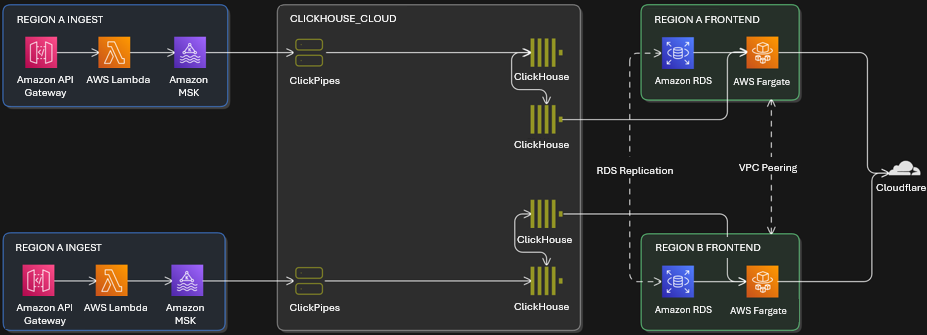
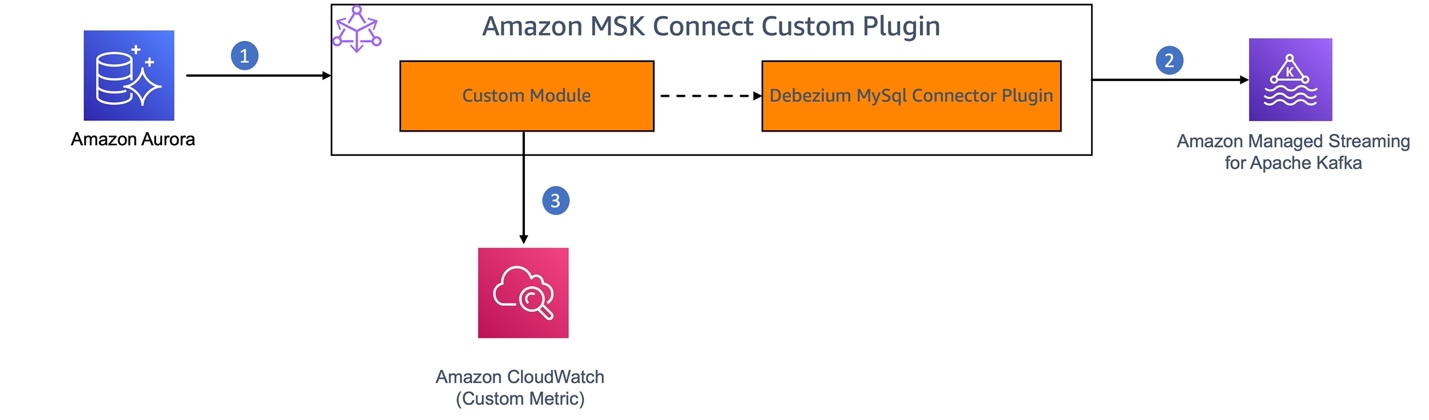
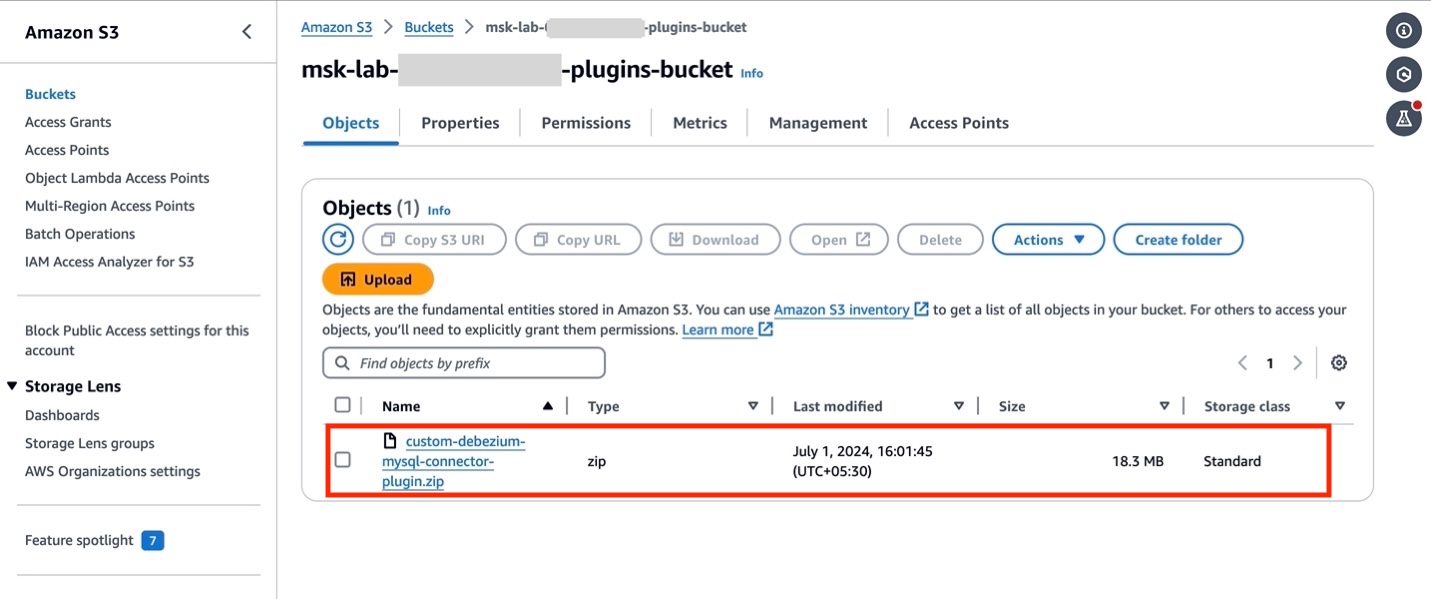
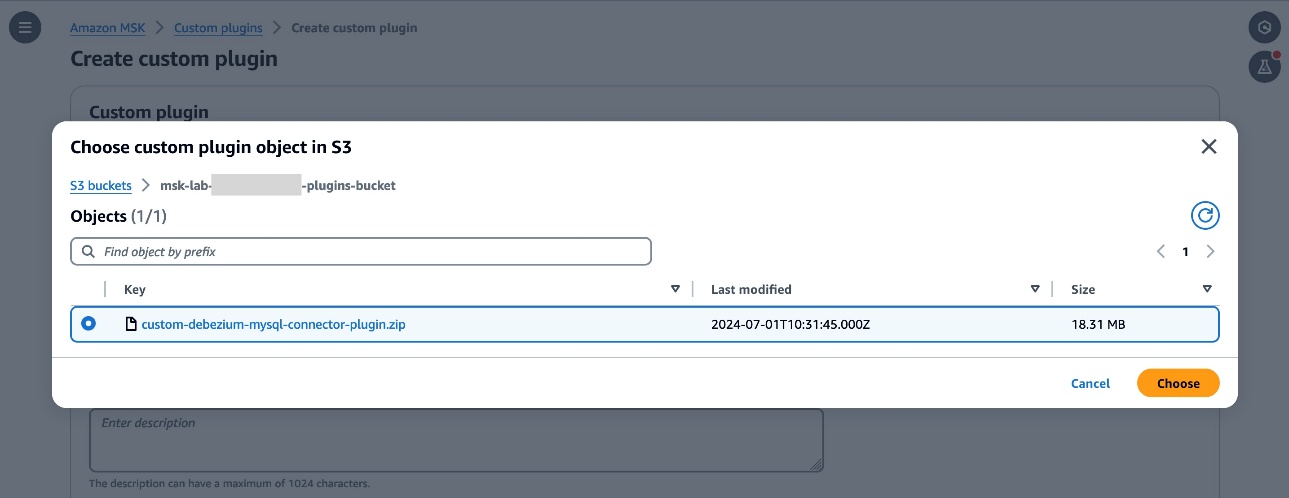
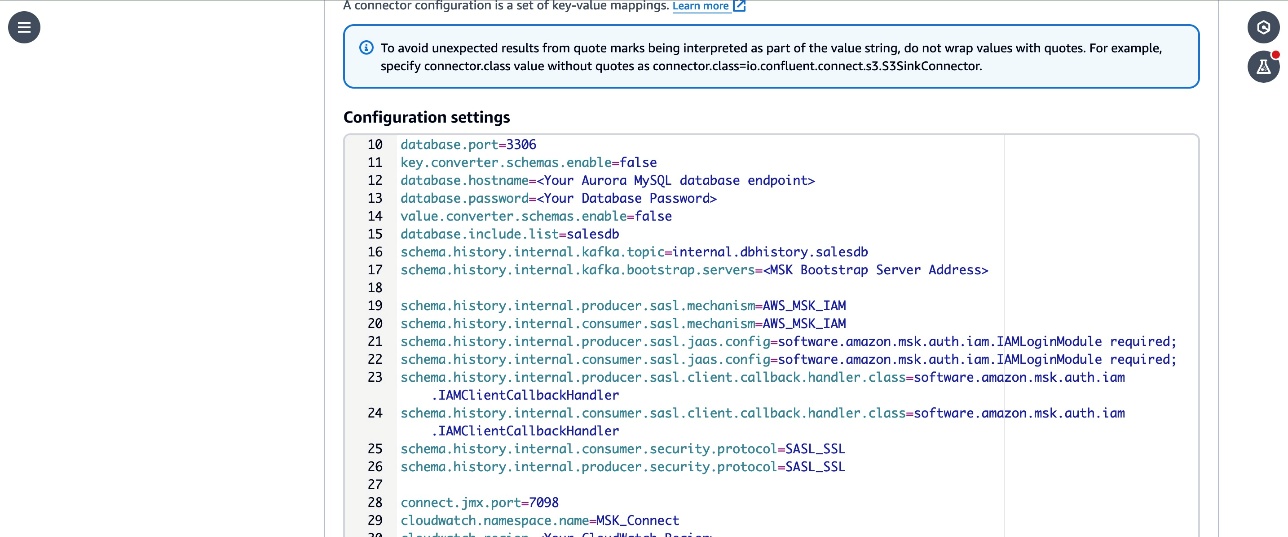
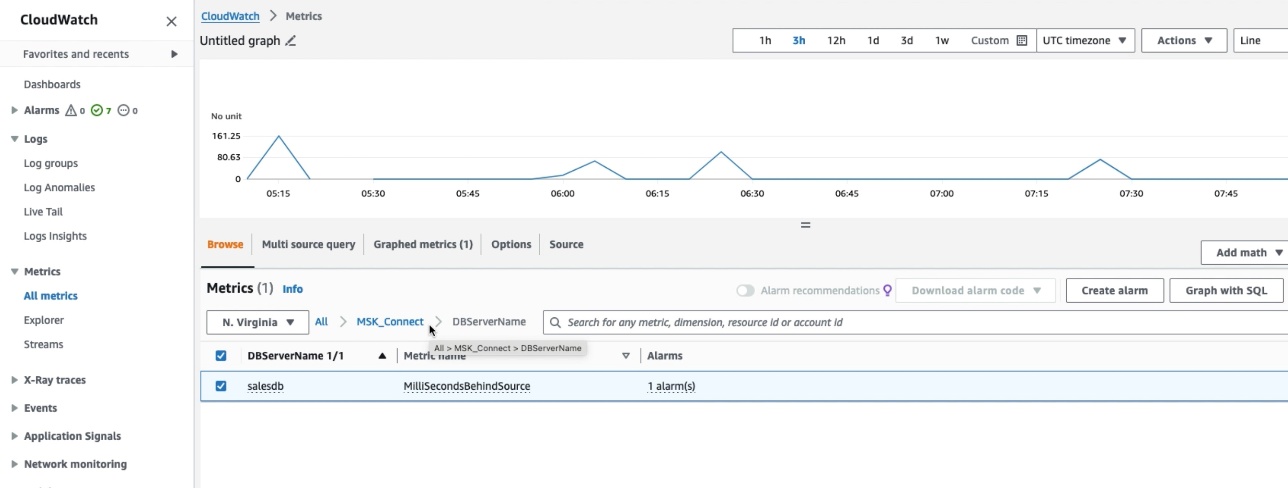
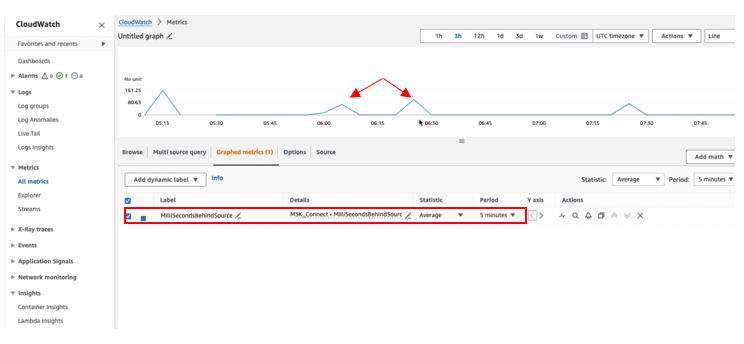
 Jaydev Nath is a Solutions Architect at AWS, where he works with ISV customers to build secure, scalable, reliable, and cost-efficient cloud solutions. He brings strong expertise in building SaaS architecture on AWS with a focus on Generative AI and data analytics technologies to help deliver practical, valuable business outcomes for customers.
 David John Chakram is a Principal Solutions Architect at AWS. He specializes in building data platforms and architecting seamless data ecosystems. With a profound passion for databases, data analytics, and machine learning, he excels at transforming complex data challenges into innovative solutions and driving businesses forward with data-driven insights.
 Sharmila Shanmugam is a Solutions Architect at Amazon Web Services. She is passionate about solving the customers’ business challenges with technology and automation and reduce the operational overhead. In her current role, she helps customers across industries in their digital transformation journey and build secure, scalable, performant and optimized workloads on AWS.
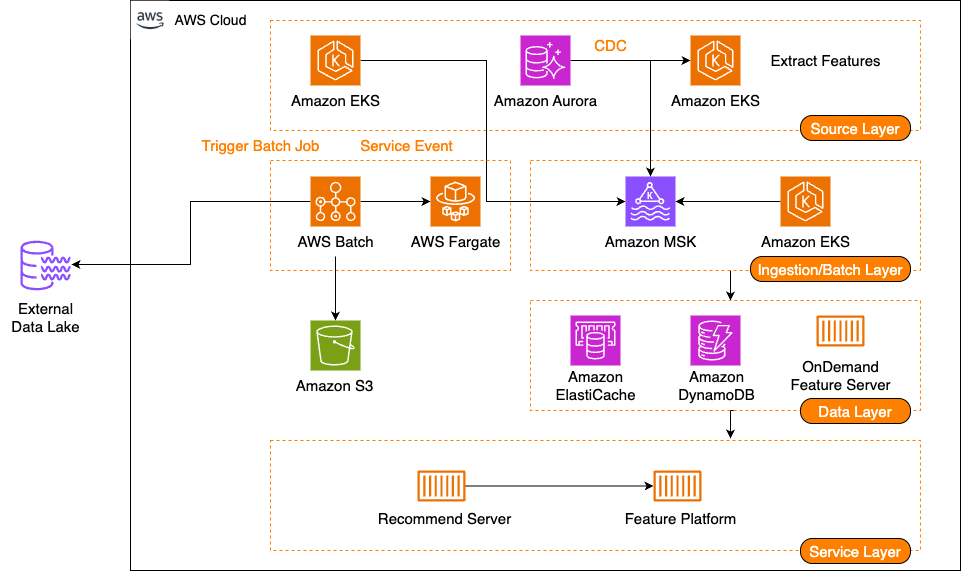
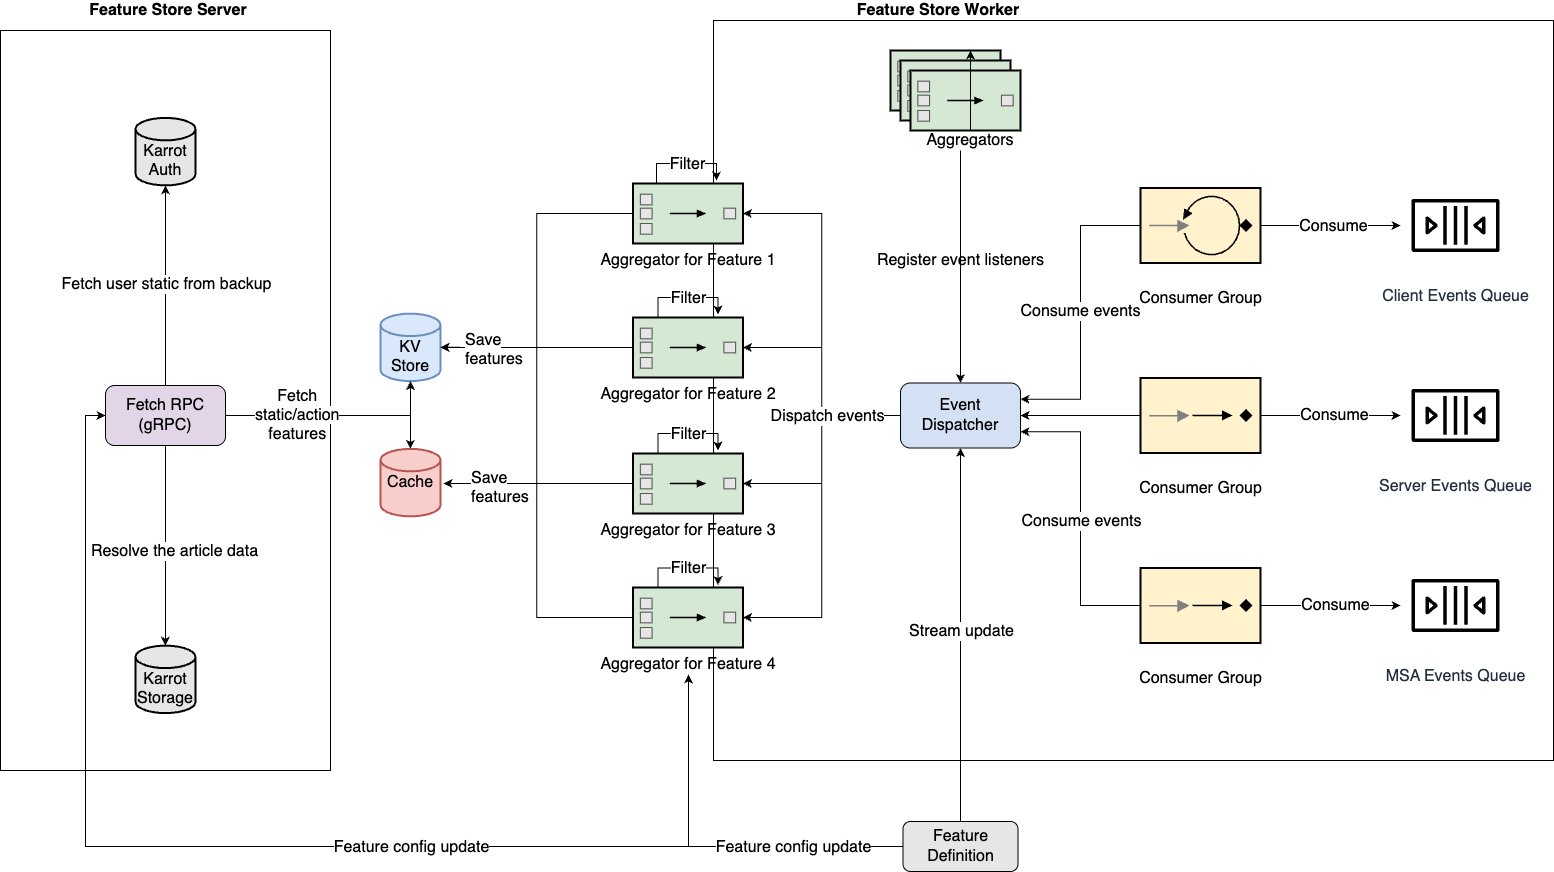
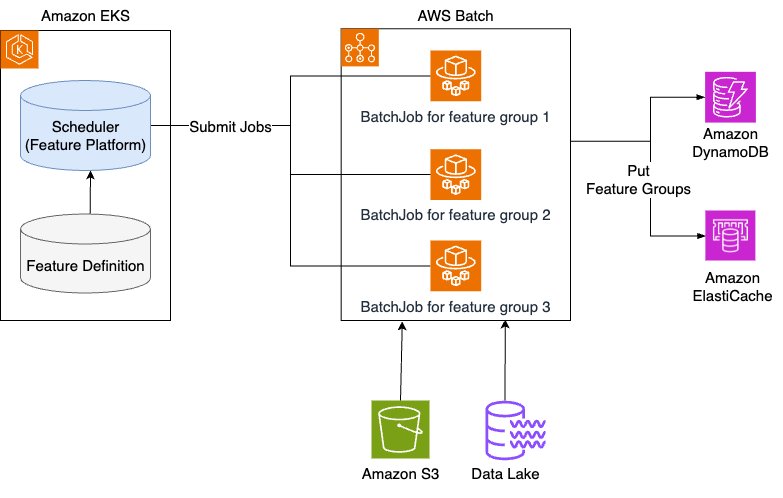
 Konstantinos Tzouvanas is a Senior Enterprise Architect on AWS, specializing in data science and AI/ML. He has extensive experience in optimizing real-time decision-making in High-Frequency Trading (HFT) and applying machine learning to genomics research. Known for leveraging generative AI and advanced analytics, he delivers practical, impactful solutions across industries.
 Marios Parthenios is a Senior Solutions Architect working with Small and Medium Businesses across Central and Eastern Europe. He empowers organizations to build and scale their cloud solutions with a particular focus on Data Analytics and Generative AI workloads. He enables businesses to harness the power of data and artificial intelligence to drive innovation and digital transformation.
 Pavlos Kaimakis is a Senior Solutions Architect at AWS who helps customers design and implement business-critical solutions. With extensive experience in product development and customer support, he focuses on delivering scalable architectures that drive business value. Outside of work, Pavlos is an avid traveler who enjoys exploring new destinations and cultures.
 John Mousa is a Senior Solutions Architect at AWS. He helps power and utilities and healthcare and life sciences customers as part of the regulated industries team in Germany. John has interest in the areas of service integration, microservices architectures, as well as analytics and data lakes. Outside of work, he loves to spend time with his family and play video games.