Amazon Web Services (AWS) is pleased to announce that the Summer 2025 System and Organization Controls (SOC) 1 report is now available. The report covers 183 services over the 12-month period from July 1, 2024 to June 30, 2025, giving customers a full year of assurance. The reports demonstrate our continuous commitment to adhering to the heightened expectations of cloud service providers.
AWS strives to continuously bring services into the scope of its compliance programs to help customers meet their architectural and regulatory needs. You can view the current list of services in scope on our Services in Scope page. As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback about SOC compliance.
To learn more about AWS compliance and security programs, see AWS Compliance Programs. As always, we value feedback and questions; reach out to the AWS Compliance team through the Contact Us page.
If you have feedback about this post, submit comments in the Comments section below.
Amazon OpenSearch Ingestion is a powerful data ingestion pipeline that AWS customers use for many different purposes, such as observability, analytics, and zero-ETL search. Many customers today push logs, traces, and metrics from their applications to OpenSearch Ingestion to store and analyze this data.
Today, we are happy to announce that OpenSearch Ingestion pipelines now support cross-account ingestion for push-based sources such as HTTP and OpenTelemetry (OTel). Organizations can now use this feature to effortlessly share data across teams. For example, many organizations have central observability teams—now these teams can create OpenSearch Ingestion pipelines and share them with other teams in their organization. You can also use this feature to ingest data into Amazon OpenSearch Service domains or Amazon OpenSearch Serverless collections in other accounts.
Previously, sharing OpenSearch Ingestion pipelines across accounts required teams to use virtual private cloud (VPC) features to share access. For example, teams could use VPC peering, which is not always feasible, or AWS Transit Gateway. The new cross-account ingestion features in OpenSearch Ingestion can simplify your deployment and reduce cost for sharing pipelines.
Solution overview
Let’s look at how to share a pipeline from a central logging account with two other development accounts (A and B). The central logging account can create an OpenSearch Ingestion pipeline using a push-based source, for example, HTTP. After creating the pipeline, a member of the central logging team can grant access to the other teams. They can use a resource policy that gives permissions to the two other team accounts to create pipeline endpoints. After making this change, the OpenSearch Ingestion pipeline is available for use by the other teams.
The following diagram illustrates this configuration.
In the following sections, we demonstrate how to implement this solution.
Prerequisites
First, the central logging account must have a VPC with two options enabled.
The development accounts that are going to connect to the pipeline also must have VPCs in the same region with the same DNS options enabled.
enableDnsSupport must be set to true
enableDnsHostnames must be set to true
Create resource policy
As the owner of the pipeline, you can create a resource policy that allows the two development accounts to create pipeline endpoints against your pipeline.
The following is an example resource policy for this scenario:
The OpenSearch Ingestion console makes it straightforward to create these policies, as shown in the following screenshot.
Create pipeline endpoint
Now that the central logging account has shared permissions on their pipeline, the development accounts can create pipeline endpoints. A pipeline endpoint is a connection from one VPC to an OpenSearch Ingestion pipeline.
The development accounts are responsible for creating the pipeline endpoints in the VPCs they want to connect from. They create this in the subnets they need and provide a security group. The security group should have an inbound rule allowing access port HTTPS over port 443 from any source that the development accounts need to ingest logs.
Development team A can create a pipeline endpoint using a command similar to the following:
Development team A can also use the OpenSearch Ingestion console to create the pipeline endpoint.
After performing this change, the VPC for development team A will have a pipeline endpoint. This pipeline endpoint now allows for ingesting data into the central logging pipeline. Now, Amazon Elastic Compute Cloud (Amazon EC2) instances, Amazon Elastic Container Service (Amazon ECS) tasks, Kubernetes pods, and other compute running in the VPC can ingest their log data into the pipeline using tools such as FluentBit.
At the same time or at a later time, development team B can create a pipeline endpoint as well. This team will create it for their own VPC.
After this, the pipeline will now have two pipeline endpoints, so both teams can ingest their log data into the central logging VPC.
Clean up
After a pipeline endpoint is created, either account can remove it. The development teams in our scenario can use the DeletePipelineEndpoint API to delete it from their accounts. Additionally, if the central logging account needs to remove a pipeline endpoint from a pipeline, it can use the RevokePipelineEndpointConnections API. Both options are available on the OpenSearch Ingestion console as well.
After the pipeline endpoints are removed, the central logging team can also remove the pipeline if they no longer need it.
Conclusion
The new pipeline endpoint feature for OpenSearch Ingestion simplifies how you can share pipelines for cross-account ingestion. This can help teams use the powerful features of OpenSearch Ingestion and open up new possibilities for teams or organizations using multiple accounts and VPCs. The new pipeline endpoint feature is available today in AWS Regions where OpenSearch Ingestion is available.
To get started with cross-account ingestion in OpenSearch Ingestion, refer to OpenSearch Ingestion documentation or try creating your first cross-account pipeline on the OpenSearch Ingestion console.
Today we are adding Qwen models from Alibaba in Amazon Bedrock. With this launch, Amazon Bedrock continues to expand model choice by adding access to Qwen3 open weight foundation models (FMs) in a full managed, serverless way. This release includes four models: Qwen3-Coder-480B-A35B-Instruct, Qwen3-Coder-30B-A3B-Instruct, Qwen3-235B-A22B-Instruct-2507, and Qwen3-32B (Dense). Together, these models feature both mixture-of-experts (MoE) and dense architectures, providing flexible options for different application requirements.
Amazon Bedrock provides access to industry-leading FMs through a unified API without requiring infrastructure management. You can access models from multiple model providers, integrate models into your applications, and scale usage based on workload requirements. With Amazon Bedrock, customer data is never used to train the underlying models. With the addition of Qwen3 models, Amazon Bedrock offers even more options for use cases like:
Code generation and repository analysis with extended context understanding
Building agentic workflows that orchestrate multiple tools and APIs for business automation
Balancing AI costs and performance using hybrid thinking modes for adaptive reasoning
Qwen3 models in Amazon Bedrock These four Qwen3 models are now available in Amazon Bedrock, each optimized for different performance and cost requirements:
Qwen3-Coder-480B-A35B-Instruct – This is a mixture-of-experts (MoE) model with 480B total parameters and 35B active parameters. It’s optimized for coding and agentic tasks and achieves strong results in benchmarks such as agentic coding, browser use, and tool use. These capabilities make it suitable for repository-scale code analysis and multistep workflow automation.
Qwen3-Coder-30B-A3B-Instruct – This is a MoE model with 30B total parameters and 3B active parameters. Specifically optimized for coding tasks and instruction-following scenarios, this model demonstrates strong performance in code generation, analysis, and debugging across multiple programming languages.
Qwen3-235B-A22B-Instruct-2507 – This is an instruction-tuned MoE model with 235B total parameters and 22B active parameters. It delivers competitive performance across coding, math, and general reasoning tasks, balancing capability with efficiency.
Qwen3-32B (Dense) – This is a dense model with 32B parameters. It is suitable for real-time or resource-constrained environments such as mobile devices and edge computing deployments where consistent performance is critical.
Architectural and functional features in Qwen3 The Qwen3 models introduce several architectural and functional features:
MoE compared with dense architectures – MoE models such as Qwen3-Coder-480B-A35B, Qwen3-Coder-30B-A3B-Instruct, and Qwen3-235B-A22B-Instruct-2507, activate only part of the parameters for each request, providing high performance with efficient inference. The dense Qwen3-32B activates all parameters, offering more consistent and predictable performance.
Agentic capabilities – Qwen3 models can handle multi-step reasoning and structured planning in one model invocation. They can generate outputs that call external tools or APIs when integrated into an agent framework. The models also maintain extended context across long sessions. In addition, they support tool calling to allow standardized communication with external environments.
Hybrid thinking modes – Qwen3 introduces a hybrid approach to problem-solving, which supports two modes: thinking and non-thinking. The thinking mode applies step-by-step reasoning before delivering the final answer. This is ideal for complex problems that require deeper thought. Whereas the non-thinking mode provides fast and near-instant responses for less complex tasks where speed is more important than depth. This helps developers manage performance and cost trade-offs more effectively.
Long-context handling – The Qwen3-Coder models support extended context windows, with up to 256K tokens natively and up to 1 million tokens with extrapolation methods. This allows the model to process entire repositories, large technical documents, or long conversational histories within a single task.
When to use each model The four Qwen3 models serve distinct use cases. Qwen3-Coder-480B-A35B-Instruct is designed for complex software engineering scenarios. It’s suited for advanced code generation, long-context processing such as repository-level analysis, and integration with external tools. Qwen3-Coder-30B-A3B-Instruct is particularly effective for tasks such as code completion, refactoring, and answering programming-related queries. If you need versatile performance across multiple domains, Qwen3-235B-A22B-Instruct-2507 offers a balance, delivering strong general-purpose reasoning and instruction-following capabilities while leveraging the efficiency advantages of its MoE architecture. Qwen3-32B (Dense) is appropriate for scenarios where consistent performance, low latency, and cost optimization are important.
Getting started with Qwen models in Amazon Bedrock To begin using Qwen models, in the Amazon Bedrock console, I choose Model Access from the Configure and learn section of the navigation pane. I then navigate to the Qwen models to request access. In the Chat/Text Playground section of the navigation pane, I can quickly test the new Qwen models with my prompts.
To integrate Qwen3 models into my applications, I can use any AWS SDKs. The AWS SDKs include access to the Amazon Bedrock InvokeModel and Converse API. I can also use these model with any agentic framework that supports Amazon Bedrock and deploy the agents using Amazon Bedrock AgentCore. For example, here’s the Python code of a simple agent with tool access built using Strands Agents:
from strands import Agent
from strands_tools import calculator

agent = Agent(
    model="qwen.qwen3-coder-480b-instruct-v1:0",
    tools=[calculator]
)

agent("Tell me the square root of 42 ^ 9")

with open("function.py", 'r') as f:
    my_function_code = f.read()

agent(f"Help me optimize this Python function for better performance:\n\n{my_function_code}")
Now available Qwen models are available today in the following AWS Regions:
Qwen3-Coder-480B-A35B-Instruct is available in the US West (Oregon), Asia Pacific (Mumbai, Tokyo), and Europe (London, Stockholm) Regions.
Qwen3-Coder-30B-A3B-Instruct, Qwen3-235B-A22B-Instruct-2507, and Qwen3-32B are available in the US East (N. Virginia), US West (Oregon), Asia Pacific (Mumbai, Tokyo), Europe (Ireland, London, Milan, Stockholm), and South America (São Paulo) Regions.
In March, Amazon Web Services (AWS) became the first cloud service provider to deliver DeepSeek-R1 in a serverless way by launching it as a fully managed, generally available model in Amazon Bedrock. Since then, customers have used DeepSeek-R1’s capabilities through Amazon Bedrock to build generative AI applications, benefiting from the Bedrock’s robust guardrails and comprehensive tooling for safe AI deployment.
Today, I am excited to announce DeepSeek-V3.1 is now available as a fully managed foundation model in Amazon Bedrock. DeepSeek-V3.1 is a hybrid open weight model that switches between thinking mode (chain-of-thought reasoning) for detailed step-by-step analysis and non-thinking mode (direct answers) for faster responses.
According to DeepSeek, the thinking mode of DeepSeek-V3.1 achieves comparable answer quality with better results, stronger multi-step reasoning for complex search tasks, and big gains in thinking efficiency compared with DeepSeek-R1-0528.
DeepSeek-V3.1 model performance in tool usage and agent tasks has significantly improved through post-training optimization compared to previous DeepSeek models. DeepSeek-V3.1 also supports over 100 languages with near-native proficiency, including significantly improved capability in low-resource languages lacking large monolingual or parallel corpora. You can build global applications to deliver enhanced accuracy and reduced hallucinations compared to previous DeepSeek models, while maintaining visibility into its decision-making process.
Here are your key use cases using this model:
Code generation – DeepSeek-V3.1 excels in coding tasks with improvements in software engineering benchmarks and code agent capabilities, making it ideal for automated code generation, debugging, and software engineering workflows. It performs well on coding benchmarks while delivering high-quality results efficiently.
Agentic AI tools – The model features enhanced tool calling through post-training optimization, making it strong in tool usage and agentic workflows. It supports structured tool calling, code agents, and search agents, positioning it as a solid choice for building autonomous AI systems.
Enterprise applications – DeepSeek models are integrated into various chat platforms and productivity tools, enhancing user interactions and supporting customer service workflows. The model’s multilingual capabilities and cultural sensitivity make it suitable for global enterprise applications.
As I mentioned in my previous post, when implementing publicly available models, give careful consideration to data privacy requirements when implementing in your production environments, check for bias in output, and monitor your results in terms of data security, responsible AI, and model evaluation.
Get started with the DeepSeek-V3.1 model in Amazon Bedrock If you’re new to using the DeepSeek-V3.1 model, go to the Amazon Bedrock console, choose Model access under Bedrock configurations in the left navigation pane. To access the fully managed DeepSeek-V3.1 model, request access for DeepSeek-V3.1 in the DeepSeek section. You’ll then be granted access to the model in Amazon Bedrock.
Next, to test the DeepSeek-V3.1 model in Amazon Bedrock, choose Chat/Text under Playgrounds in the left menu pane. Then choose Select model in the upper left, and select DeepSeek as the category and DeepSeek-V3.1 as the model. Then choose Apply.
Using the selected DeepSeek-V3.1 model, I run the following prompt example about technical architecture decision.
Outline the high-level architecture for a scalable URL shortener service like bit.ly. Discuss key components like API design, database choice (SQL vs. NoSQL), how the redirect mechanism works, and how you would generate unique short codes.
You can turn the thinking on and off by toggling Model reasoning mode to generate a response’s chain of thought prior to the final conclusion.
Amazon SageMaker Unified Studio is a single data and AI development environment that brings together data preparation, analytics, machine learning (ML), and generative AI development in one place. By unifying these workflows, it saves teams from managing multiple tools and makes it straightforward for data scientists, analysts, and developers to build, train, and deploy ML models and AI applications while collaborating seamlessly.
In SageMaker Unified Studio, a project is a boundary where you can collaborate with other users to work on a business use case. A blueprint defines what AWS tools and services members of a project can use as they work with their data. Blueprints are defined by an administrator and are powered by AWS CloudFormation. Instead of manually piecing together project structures or workflow configurations, teams can rapidly spin up secure, compliant, and consistent analytics and AI environments. This streamlined approach significantly reduces setup time and provides standardized workspaces across the organization. Out of the box, SageMaker Unified Studio comes with several default blueprints.
We recently launched the custom blueprints feature in SageMaker Unified Studio. Organizations can now incorporate their specific dependencies, security controls using their own managed AWS Identity and Access Management (IAM) policies, and best practices, making it straightforward for them to align with internal standards. Because they’re defined through infrastructure as code (IaC), blueprints are straightforward to version control, share across teams, and evolve over time. This speeds up onboarding and keeps projects consistent and governed, no matter how big or distributed your data organization becomes.
For enterprises, this means more time focusing on insights, models, and innovation. The custom blueprints feature is designed to help teams move faster and stay consistent while maintaining their organization’s security controls and best practices. In this post, we show how to get started with custom blueprints in SageMaker Unified Studio.
Solution overview
We provide a CloudFormation template to implement a custom blueprint in SageMaker Unified Studio. The template deploys the following resources in the project environment:
The CloudFormation template uses parameters that are reserved to your SageMaker environment, such as datazoneEnvironmentEnvironmentId, datazoneEnvironmentProjectId, s3BucketArn, and privateSubnets. These parameters are automatically populated by SageMaker when creating the project. The parameters also help in retrieving other environment variables, such as SecurityGroupIds, as shown in the following snippets.
The following code illustrates defining reserved environment parameters:
"Parameters": {
        "datazoneEnvironmentEnvironmentId": {
            "Type": "String",
            "Description": "EnvironmentId for which the resource will be created for."
        },
        "datazoneEnvironmentProjectId": {
            "Type": "String",
            "Description": "DZ projectId for which project the resource will be created for."
        },
        "s3BucketArn": {
            "Type": "String",
            "Description": "Project S3 Bucket ARN"
        },
        "privateSubnets": {
            "Type": "String",
            "Description": "Project Private Subnets"
        }
}
The following code illustrates using reserved environment parameters to import other necessary values:
By default, SageMaker Unified Studio creates a project role and attaches several managed policies to the role. These managed policies are defined in the tooling blueprint. With custom blueprints, you can configure and attach your own IAM policies, in addition to the default policies, to the project role. To do this, include the IAM policies in your CloudFormation template and use the Export feature in the Outputs section, as shown in the following code. SageMaker Unified Studio gathers the policy information and adds it to the project role.
"GlueAccessManagedPolicy": {
            "Description": "ARN of the created managed policy",
            "Value": {
                "Ref": "GlueAccessManagedPolicy"
            },
            "Export": {
                "Name": {
                    "Fn::Sub": "datazone-managed-policy-glue-${glueDbName}-${datazoneEnvironmentEnvironmentId}"
                }
            }
        },
"RedshiftAccessManagedPolicy": {
            "Description": "ARN of the created Redshift managed policy",
            "Value": {
                "Ref": "RedshiftAccessManagedPolicy"
            },
            "Export": {
                "Name": {
                    "Fn::Sub": "datazone-managed-policy-redshift-${redshiftWorkgroupName}-${datazoneEnvironmentEnvironmentId}"
                }
            }
        }
Create custom blueprint
Complete the following steps to create a custom blueprint using the CloudFormation template:
On the Amazon SageMaker console, open the domain where you want to create a custom blueprint.
On the Blueprints tab, choose Create.
Under Name and description, enter a name and optional description.
Under Upload CloudFormation template, select Upload a template file and upload the provided template.
Choose Next. SageMaker will automatically detect the reserved parameters defined in the template, as shown in the following screenshot.
For Editable parameters, edit the Value column if necessary, and specify whether the values can be editable at the time of project creation.
Choose Next. As shown in the following screenshot, the reserved parameters described earlier are not shown on this page.
Select Enable blueprint.
Choose the provisioning role to be used by SageMaker to provision the environment resources.
Choose the domain units authorized to use the blueprint.
Choose Next.
Review the blueprint information and choose Create blueprint.
Create project profile
Complete the following steps to create a custom project profile that includes the custom blueprint created in the previous section:
On the SageMaker console, open your domain.
On the Project profiles tab, choose Create.
Enter the project profile name and optional description.
Select Custom create.
Choose the blueprints to be included in the project profile, including the custom blueprint you created in the previous section.
Choose the account and AWS Region to be used.
Choose the authorized users.
Select Enable project profile on creation.
Choose Create project profile.
Create project
Complete the following steps to create a new project that is based on the custom project profile and custom blueprint created in the previous sections:
In the SageMaker Unified Studio environment, choose Create project.
Enter a project name and optional description.
For Project profile, choose the profile created in the previous section.
Choose Continue.
On the Customize blueprint parameters page, review the parameters, modify as necessary, and choose Continue.
Review your selections and choose Create project.
SageMaker Unified Studio will create the project environments with the resources defined in your custom blueprint.
It will also attach the custom IAM policies defined and add them to the project role, as shown in the following screenshot.
Clean up
To avoid incurring additional costs, complete the following steps:
In this post, we discussed custom blueprints, a new option during administrator setup in SageMaker Unified Studio. We showed how to create new custom blueprints and create custom project profiles that include the newly created custom blueprints. We also demonstrated how to create projects that implement custom blueprints.
Custom blueprints in SageMaker Unified Studio are intended to streamline and standardize data, analytics and AI workflows. By helping organizations create templated environments with preconfigured resources, security controls, and best practices, custom blueprints can reduce setup time while providing consistency and compliance across projects.
Organizations can now enforce their specific security standards and access controls at the project level using the ability to incorporate custom IAM policies directly into these blueprints. This granular control over permissions helps organizations create projects that adhere to corporate security policies right from inception. Custom blueprints can help you scale analytics and AI/ML operations securely, by including tooling designed to version control these templates, share them across teams, and automatically apply custom IAM policies.
To learn more about custom blueprints in SageMaker Unified Studio, refer to Custom blueprints.
Serverless applications often comprise multiple AWS services, such as AWS Lambda, Amazon Simple Queue Service (Amazon SQS), Amazon EventBridge, and Amazon DynamoDB. Although serverless architectures make it easy to build applications that are generally simple to operate and scale, testing them requires extra steps for developers. Recently, AWS brought you the capability to help developers remotely debug Lambda functions to accelerate the development process. Today, we’re excited to announce new capabilities that further simplify the local testing experience for Lambda functions and serverless applications through integration with LocalStack, an AWS Partner, in the AWS Toolkit for Visual Studio Code.
In this post, we will show you how you can enhance your local testing experience for serverless applications with LocalStack using AWS Toolkit.
Challenges with local serverless development
When building serverless applications with infrastructure as code (IaC) tools like the AWS Serverless Application Model (AWS SAM), developers often face challenges during local integration testing of applications that depend on interactions across multiple AWS services. These friction points slow down the critical code-test-debug cycle. Developers might encounter the following common roadblocks:
Cloud-based validation slows iteration – Developers previously needed to deploy AWS SAM templates to the cloud to test changes, introducing delays in feedback loops. AWS research shows that developers spend considerable time on deployment and testing, rather than writing code.
Tool context switching adds friction – Developers routinely shift between integrated development environments (IDEs), command line interfaces (CLIs), and resource emulators like LocalStack, leading to fragmented workflows.
Manual setup increases configuration complexity – Port mapping and code edits for local service integration tests can introduce inconsistencies between local and cloud environments.
Service integration debugging is limited – Troubleshooting Lambda functions in the context of AWS service integrations, such as DynamoDB, Amazon Simple Storage Service (Amazon S3), or Amazon SQS, requires manual configuration, extending the duration of troubleshooting efforts.
These challenges directly impact developer productivity and make local testing of integrated serverless applications complex.
Solution overview
Starting today, AWS helps simplify local serverless development by integrating LocalStack directly into the AWS Toolkit for VS Code. This integration helps developers test and debug serverless applications—defined using IaC tools like AWS SAM—entirely within their IDE. The enhanced local testing experience delivers four major improvements:
Integrated LocalStack experience – Connect to LocalStack directly within VS Code and manage local resources alongside cloud resources through a unified interface.
Emulated service interactions – Test Lambda functions with their interactions with other AWS services like Amazon SQS, DynamoDB, and EventBridge locally.
Simplified debugging – Start debugging sessions with LocalStack emulated environment, with a single click – no manual port configurations or code changes required, streamlining the debugging workflow.
Streamlined workflow – Deploy, test, and debug serverless applications without leaving the IDE, avoiding context switching between tools.
To set up LocalStack in VS Code (either the free version supporting over 30 core services like Lambda, Amazon S3, DynamoDB, Amazon SQS, and Amazon API Gateway, or the Ultimate version with over 110 services and advanced debugging features) you need essential development tools, including Docker, the AWS Command Line Interface (AWS CLI), AWS SAM CLI, and your preferred IDE such as VS Code. This combination enables full local integration testing of AWS services, including Lambda functions, messaging queues, databases, event-driven architectures, and serverless workflows, so you can develop and test your entire AWS application stack locally before deploying to the cloud.
Automated setup process
LocalStack is a cloud service emulator that you can use to run AWS applications locally for testing and development. To enhance your local testing capabilities, you can install the LocalStack VSCode Extension directly from AWS Walkthrough in AWS Toolkit, which offers a streamlined setup process through an intelligent wizard. After installation, the extension automatically detects whether LocalStack is configured on your system and prompts you to run the setup wizard through a notification. The entire process is quick and requires no manual configuration.
LocalStack extension has an integrated authentication wizard, that simplifies the process of connecting your development environment to LocalStack. During setup, the wizard opens a browser-based authentication flow and maintains an active connection until authentication completes. After it’s verified, it securely stores the authentication token in the ~/.localstack/auth.json file, enabling communication between your local environment and LocalStack services.
The wizard also checks if LocalStack AWS CLI profiles exist, and if not found, automatically creates them by updating the ~/.aws/config and ~/.aws/credentials files with LocalStack-specific endpoints and credentials. This seamless integration of AWS profiles enhances the development workflow by allowing developers to easily switch between different AWS environments, including the local LocalStack setup. By leveraging these profiles, developers can effortlessly point their AWS CLI or SDK to the appropriate endpoint, whether it’s a real AWS account or the LocalStack instance running on their machine. This configuration not only ensures a clear separation between local and cloud environments but also minimizes the risk of cross-environment interference. The automatic creation of these profiles streamlines the setup process, reducing manual configuration errors and saving valuable development time. Visual Studio Code (VS Code) provides real-time feedback throughout the setup. The status bar initially displays an error or warning indicator when LocalStack is not configured and then transitions to a normal or connected state once a successful connection is established. After setup completes, you’re ready to deploy, test, and debug serverless applications locally—without additional configuration. These settings persist across VS Code sessions, so the setup process is a one-time task.The following figure illustrates the process to start and verify LocalStack from VS Code.
To learn more, including installation steps, configuration examples, and troubleshooting guidance, visit the LocalStack Docs.
Test a serverless application
To demonstrate the enhanced local testing capabilities, let’s explore a practical serverless pattern: building and testing an event-driven order processing system that integrates Lambda with Amazon SQS, API Gateway, and Amazon Simple Notification Service (Amazon SNS). The application processes orders through an event-driven workflow: orders are submitted through API Gateway to an SQS queue and processed by a Lambda function, and the status is published to Amazon SNS to trigger customer email notifications.
After you set up LocalStack in VS Code, you can test your entire serverless workflow without deploying to the cloud:
Deploy locally – Use the LocalStack AWS profile to deploy your AWS SAM application. The process mirrors cloud deployment but targets local endpoints. You can use the Application builder pane to initiate the deployment to LocalStack environment. The following figure illustrates the process of deploying a sample serverless application.
Debug Lambda function deployed in LocalStack – Set breakpoints in your Lambda function and step through execution using VS Code’s integrated debugger. With the AWS Toolkit extension, you can invoke your Lambda with one click and inspect live interactions across services, all while running against a LocalStack container on your machine. This setup makes it possible to debug your AWS applications in a controlled, local environment that mimics the cloud infrastructure, without the need for deploying actual AWS services.
Validate end-to-end Flows – Test complete workflows from message ingestion through processing and notification, confirming all service integrations work correctly before cloud deployment.
For an in-depth technical demonstration of this LocalStack integration, refer to this youtube video.
Best practices for local Lambda function testing
In this section, we discuss various strategies and best practices for local Lambda function testing.
Optimizing your development workflow
Consider the following strategies to optimize your development workflow:
Start with a strong testing foundation – Use the AWS SAM CLI to perform unit tests that validate the core programmatic and business logic of your Lambda functions. Isolating function behavior early helps identify logic errors before introducing external dependencies.
Establish environment parity early in the development process – Many production issues stem from discrepancies between local and cloud environments. Use consistent service versions, configurations, and data structures across environments to confirm that what works locally behaves the same in production.
Adopt IaC from day one – Whether you choose AWS SAM, AWS CloudFormation, or another IaC framework, defining your application infrastructure as code reduces configuration drift and makes your deployments reproducible across teams and environments.
Apply a progressive testing strategy – Follow a structured testing pyramid that starts with fast, isolated unit tests and builds up to broader integration and system-level validation. This layered approach helps you catch issues earlier—when they’re easier and less expensive to fix—while still providing full application coverage.
A strategic approach to testing
Testing should be an integrated part of your serverless development workflow—not an afterthought. Successful teams implement layered testing strategies that use both local and cloud environments to strike a balance between speed and accuracy:
Begin with unit tests that focus on isolated function logic. Use tools like the AWS SAM CLI, AWS Toolkit for VS Code and LocalStack extensions to run and debug functions locally.
After validation, proceed to local integration testing using LocalStack to confirm how your Lambda functions interact with services such as Amazon SQS, DynamoDB, and Amazon SNS. These tests typically complete within minutes and catch most service integration issues before they reach production.
After local testing, validate your application in the actual AWS environment. Cloud testing helps surface issues not present in local emulation, such as AWS Identity and Access Management (IAM) permission mismatches, Amazon Virtual Private Cloud (Amazon VPC) networking challenges, or service-specific nuances such as Lambda concurrency. For troubleshooting issues in the cloud environment, you can also remotely debug your Lambda functions using AWS Toolkit for VS Code.
Lastly, conduct performance testing in AWS to assess how your application handles real-world traffic. These longer-running tests help validate scaling behavior and system resilience under load.
The result is higher-quality applications delivered faster, with fewer production surprises and more confident deployments.
Security considerations
When using LocalStack for local development, follow these security best practices:
Isolate the local environment – Use Docker networking to restrict LocalStack access and bind services to localhost to prevent external connections.
Use placeholder credentials – Use test credentials (for example, test/test) instead of real AWS credentials.
Protect your data – Use synthetic or anonymized datasets instead of production data and regularly purge local data stores to reduce risk.
When to use local versus cloud testing
Although local testing offers significant advantages, it’s important to understand when to use it versus testing in the cloud. The following table lists the potential use cases for each strategy.
Testing Scenario
Local Testing
Cloud Testing
Reason
Function logic validation
✓
Fast feedback for core business logic
Service integration testing
✓
Quick validation of AWS service interactions
Rapid iteration during development
✓
Immediate feedback without deployment overhead
Cost-sensitive development environments
✓
Minimizes cloud resource costs during development
Offline development scenarios
✓
No internet connectivity required
Performance and scalability testing
✓
Requires actual AWS infrastructure for accurate results
IAM permission validation
✓
LocalStack doesn’t fully replicate IAM behavior
VPC networking scenarios
✓
Network configurations can’t be accurately emulated
Production-like load testing
✓
Real performance metrics only available in AWS
Final validation before deployment
✓
Supports compatibility with actual AWS environment
Conclusion
In this post, we discussed how to streamline local testing for AWS Serverless applications using LocalStack and the AWS Toolkit for VS Code. By running and debugging serverless applications directly in your IDE, you can reduce context switching, test complex integrations locally, and catch issues earlier—without deploying to the cloud.
We also showed how to apply progressive testing strategies that combine local emulation with cloud validation, optimize development costs, and build event-driven workflows with confidence.These enhancements lead to faster test cycles, lower development costs, and higher-quality deployments—all while staying fully in control of your development environment.
Have questions or feedback about this post? Connect with us on the AWS Compute Blog or join the AWS Developer community.
Amazon Web Services (AWS) successfully completed an onboarding audit with no findings for ISO 9001:2015, 27001:2022, 27017:2015, 27018:2019, 27701:2019, 20000-1:2018, and 22301:2019, and Cloud Security Alliance (CSA) STAR Cloud Controls Matrix (CCM) v4.0. EY CertifyPoint auditors conducted the audit and reissued the certificates on August 13, 2025. The objective of the audit was to enable AWS to expand their ISO and CSA STAR certifications to include AWS Resource Explorer and AWS Incident Response to their scope. The ISO standards cover areas including quality management, information security, cloud security, privacy protection, service management, and business continuity. The certifications demonstrate AWS’s commitment to maintaining robust security controls and protecting customer data across our services.
During this onboarding audit, we added two additional AWS services to the scope since the last certification issued on May 26, 2025. The following are the two additional services:
For a full list of AWS services that are certified under ISO and CSA Star, see the AWS ISO and CSA STAR Certified page. Customers can also access the certifications in the AWS Management Console through AWS Artifact.
If you have feedback about this post, submit comments in the Comments section below.
AWS recently announced that Amazon SageMaker now offers Amazon Simple Storage Service (Amazon S3) based shared storage as the default project file storage option for new Amazon SageMaker Unified Studio projects. This feature addresses the deprecation of AWS CodeCommit while providing teams with a straightforward and consistent way to collaborate on project files across the integrated development tools in SageMaker.
This new Amazon S3 storage option provides the following benefits:
Simplified collaboration – File sharing between project members directly without Git operations
Clear workspace separation – Built-in personal storage separation with Amazon Elastic Block Store (Amazon EBS) volumes
Global availability – Available in AWS Regions where SageMaker is supported
Although Amazon S3 is the default option for file storage, you can also use Git version control for more robust source control capabilities.
In this post, we discuss this new feature and how to get started using Amazon S3 shared storage in SageMaker Unified Studio.
Solution overview
When you create a new SageMaker Unified Studio domain, the service automatically configures Amazon S3 storage as your default project storage option. Each project receives a dedicated shared location in Amazon S3, accessible to project members, following the structure [bucket]/[domain-id]/[project-id]/shared/.
SageMaker tools JupyterLab and Code Editor provide the following to users:
A personal EBS volume for individual work in JupyterLab and Code Editor tools
A mounted shared folder containing the project’s Amazon S3 shared storage
Clear separation between personal and shared spaces
The shared storage is accessible across SageMaker integrated development tools:
JupyterLab and Code Editor show shared files along with personal files
Query Editor filters for relevant SQL notebooks
Visual ETL provides direct access to shared extract, transform, and load (ETL) workflows
Files saved to the shared location are immediately visible and available to project members. Users can continue working with personal files in their EBS volumes in tools like JupyterLab and Code Editor and explicitly move files to shared storage when ready to collaborate.If you want to use Git for collaboration, you can continue to do so by integrating projects with your GitHub version control, GitLab version control, or managed Bitbucket repositories.
Migration and version control options
For teams currently using Amazon CodeCommit, existing projects will remain fully functional. New projects will default to Amazon S3 storage. If you want to have version control for Amazon S3 based projects, you can enable versioning in Amazon S3 directly.
Prerequisites
You will need to complete the following prerequisites before you can follow the instructions in the next section:
To begin using Amazon S3 shared storage, complete the following steps:
Create a new SageMaker Unified Studio domain.
Create a new project (Amazon S3 storage is the default file storage option).
Open the new project and choose JupyterLab from the Build menu.
Save the new notebook you just created.
Rename the file.
After the project is saved, project users can view the saved notebook in the Project files section under the S3 path [bucket]/[domain-id]/[project-id]/shared/.
Enable version control using Git
To enable version control using Git, complete the following steps:
On the SageMaker console, create a new project profile.
Provide the necessary details for your project profile.
In the Project files storage section, the Amazon S3 option is selected by default. To enable version control for the project, you can use existing Git repository connections by selecting Git repository.
Use shared storage in Query Editor
To use the shared storage feature in Query Editor, complete the following steps:
Choose Query Editor from the Build menu.
Compose your query, and on the Actions menu, choose Save to save the query to shared storage.
Navigate back to the Project files section, where you can view the query notebook files under the S3 path [bucket]/[domain-id]/[project-id]/shared/.
Use shared storage in Visual ETL flows
To use the shared storage feature in Visual ETL flows, complete the following steps:
Choose Visual ETL flows from the Build menu.
Develop your ETL workflow and save the code to the project.
Navigate back to the Project files section, where you can view the files under the S3 path [bucket]/[domain-id]/[project-id]/shared/jobs/uploads/<ETL name>.
Clean up
Make sure you remove the SageMaker Unified Studio resources to mitigate any unexpected costs. This involves a few steps:
Delete the projects.
Delete the domain.
Delete the S3 bucket named amazon-datazone-AWSACCOUNTID-AWSREGION-DOMAINID
Conclusion
The launch of Amazon S3 shared storage in SageMaker represents another step in simplifying the analytics and machine learning (ML) development experience for our customers. By reducing the complexity of Git operations while maintaining robust collaboration capabilities, teams can now focus on building and deploying analytics and ML solutions faster. The feature is now available in Regions where SageMaker is available.
For detailed information about this feature, including setup instructions and best practices, refer to Unified storage in Amazon SageMaker Unified Studio. Share your feedback on this feature in the comments section.
In our previous blog post (Part 1 of our key replication series), Automatically replicate your card payment keys across AWS Regions, we explored an event-driven, serverless architecture using AWS PrivateLink to securely replicate card payment keys across AWS Regions. That solution demonstrated how to build a custom replication framework for payment cryptography keys.
Based on customer feedback requesting a more automated, no-code approach, we’re excited to announce an additional option to this capability with Multi-Region keys for AWS Payment Cryptography in Part 2 of our series.
By using this new feature, you can automatically synchronize payment cryptography keys from a primary Region to other Regions that you select, improving resilience and availability of payment applications. You can also choose between account-level replication or key-level replication, giving more flexibility in how to manage payment keys across Regions.
Multi-Region keys: Overview and benefits
The new Multi-Region key replication feature for AWS Payment Cryptography offers you flexible control over your key replication strategy through the following primary capabilities:
Control whether keys are replicated
Select specific Regions for key replication
Manage replication configuration changes
Configure either account-level or key-level replication to meet business needs
Multi-Region keys help deliver several benefits for global payment operations, including:
Improved availability: Access your payment keys even if a Region becomes unavailable
Disaster recovery: Maintain business continuity with replicated keys across Regions
Global operations: Support payment processing across multiple geographic regions
Simplified management: Centralized control with distributed availability
Consistent key IDs: The same key ID across Regions simplifies application development
Configuration options
Payment Cryptography provides two distinct methods for configuring Multi-Region key replication, giving flexibility to implement a strategy that best fits your organization’s needs. You can choose between a broad, account-level approach or a more granular, key-level method.
Account-level
With account-level configuration, AWS automatically replicates exportable symmetric keys created in your Payment Cryptography account from your designated primary Region to other Regions you specify. This simplifies key management in multi-Region deployments, provides consistent key availability in the Regions that you specify, and reduces the operational overhead of key management.
To configure account-level replication using the AWS Command Line Interface (AWS CLI), use the new enable-default-key-replication-regions API to set the Regions where AWS will replicate your keys. To remove Regions from your default replication list, use the disable-default-key-replication-regions API.
Note: Only symmetric keys created after the account-level replication is enabled will be replicated.
Key-level replication
By using key-level replication, you can achieve more granular control by:
Designating specific keys as multi-Region keys
Defining custom replication targets for each multi-Region key
Maintaining Region-specific keys when needed
Note: Within each Region, Payment Cryptography maintains redundancy of your keys across multiple Availability Zones for high availability. Multi-Region key replication extends across geographic boundaries, giving you additional resilience against Regional outages while maintaining control over where your keys are stored.
You can specify replication Regions during key creation using the --replication-regions parameter, using the AWS CLI, with the create-key or import-key APIs. For existing keys, you can use the new add-key-replication-regions and remove-key-replication-regions APIs to manage which regions receive your replicated keys.
Important: When you specify replication Regions during key creation, these settings take precedence over default replication Regions configured at the account level.
How it works
Figure 1 shows the process when you replicate a key in Payment Cryptography.
The key is created in your designated primary Region
Payment Cryptography automatically replicates the key material asynchronously to the specified replica Regions
The replicated keys maintain the same key ID across Regions; only the Region portion of the Amazon Resource Name (ARN) changes
The key in the primary Region is marked with MultiRegionKeyType: PRIMARY
Keys in replica Regions are marked with MultiRegionKeyType: REPLICA and include a reference to the primary Region
When deleting a key, its deletion cascades from the primary to replica Regions
Figure 1: Representation of key replication from us-east-1 to us-west-2
Example: Creating a multi-Region key at key level
The following is an example of creating a card verification key (CVK) in the primary Region (us-east-1) with replication to us-west-2:
When using multi-Region keys, several important aspects should be considered. Multi-Region key replication supports only symmetric keys with the exportable attribute enabled, and asymmetric keys are not supported. For billing purposes, AWS bills per key per Region, which means replicating to three Regions incurs costs for the primary key plus costs for each key in the replica Regions.
Key aliases and tags require separate management in each Region because they are not part of the replication process. While primary keys support modifications and updates, replica keys are read-only copies that support only cryptographic operations. Modifications must be made to the key in the primary Region, and Payment Cryptography automatically propagates these changes to the replica Regions. Monitor the replication status to confirm successful synchronization of these changes.
The deletion process for multi-Region keys follows specific behavior patterns that are important to understand. When a primary key is scheduled for deletion, associated replica keys are deleted immediately. The primary key enters a pending deletion state with a minimum 3-day waiting period, during which the deletion can be canceled. However, if you restore the primary key by canceling its deletion, you will need to re-enable replication to recreate the replica keys in your desired Regions. After the 3-day waiting period expires, the primary key is permanently deleted and becomes unrecoverable. Note that deleting a replica key affects only that specific Region and does not impact the primary key or other replica keys.
Multi-Region key replication operates with eventual consistency. When creating new keys or making changes to existing keys, these updates might not appear immediately across all Regions. Applications should be designed to handle this eventual consistency model and not assume immediate availability of keys or key changes in replica Regions. If your application requires strong consistency, implement polling mechanisms using the GetKey API to verify that changes have been synchronized before proceeding with key operations.
Logging and monitoring
Payment Cryptography logs API activity through AWS CloudTrail, which now includes new events and attributes specific to Multi-Region key replication.
New CloudTrail event
The service logs a new event type called SynchronizeMultiRegionKey, which appears in primary and replica Regions.
Primary Region events:
Two SynchronizeMultiRegionKey events are logged in the primary Region for each replication Region defined:
To start using Multi-Region key replication in Payment Cryptography:
Determine your primary Region.
Determine your replica Regions and if you will use account-level or key-level configuration.
Create new exportable symmetric keys or update existing keys to use the Multi-Region key replication feature.
Update your applications to use the consistent key IDs across Regions.
Conclusion
The new Multi-Region key replication feature in Payment Cryptography enhances our automatic key replication capabilities, providing improved resilience and simplified management for global payment applications. This feature helps make sure your payment cryptography keys are available when and where you need them, with the flexibility to choose between account-level or key-level replication strategies.
We’re pleased to announce the completion of our annual AWS Outsourced Service Provider’s Audit Report (OSPAR) audit cycle on August 7, 2025, based on the newly enhanced version 2.0 guidelines (OSPAR v2.0). AWS is the first global cloud service provider in Singapore to obtain the report using the new OSPAR v2.0 guidelines.
The Association of Banks in Singapore (ABS) established the Guidelines on Control Objectives and Procedures for Outsourced Service Providers (ABS Guidelines) to provide baseline controls criteria that outsourced service providers (OSPs) operating in Singapore should have in place. ABS enhanced the ABS Guidelines to version 2.0, which OSPs—such as AWS—need to comply with for the audit period commencing on or after January 1, 2025. The enhanced ABS Guidelines integrate key elements from the Monetary Authority of Singapore (MAS) regulatory updates on cyber hygiene, technology risk management, and business continuity management, and include new control domains such as data security, cryptography, software application development and management, and business continuity management.
The 2025 OSPAR certification cycle includes the addition of seven new services in scope, bringing the total number of services in scope to 170 in the AWS Asia Pacific (Singapore) Region. Newly added services in scope include the following:
Successfully completing the OSPAR assessment demonstrates that AWS continues to maintain a robust system of controls to meet these guidelines. This underscores our commitment to fulfill the security expectations for cloud service providers set by the financial services industry in Singapore.Customers can use OSPAR to streamline their due diligence processes, thereby reducing the effort and costs associated with compliance. OSPAR remains a core assurance program for our financial services customers because it is closely aligned with local regulatory requirements from MAS.
As always, we’re committed to bringing new services into the scope of our OSPAR program based on your architectural and regulatory needs. If you have questions about the OSPAR report, contact your AWS account team.
If you have feedback about this post, submit comments in the Comments section below.
Developers and machine learning (ML) engineers can now connect directly to Amazon SageMaker Unified Studio from their local Visual Studio Code (VS Code) editor. With this capability, you can maintain your existing development workflows and personalized integrated development environment (IDE) configurations while accessing Amazon Web Services (AWS) analytics and artificial intelligence and machine learning (AI/ML) services in a unified data and AI development environment. This integration provides seamless access from your local development environment to scalable infrastructure for running data processing, SQL analytics, and ML workflows. By connecting your local IDE to SageMaker Unified Studio, you can optimize your data and AI development workflows without disrupting your established development practices.
In this post, we demonstrate how to connect your local VS Code to SageMaker Unified Studio so you can build complete end-to-end data and AI workflows while working in your preferred development environment.
Solution overview
The solution architecture consists of three main components:
Local computer – Your development machine running VS Code with AWS Toolkit for Visual Studio Code and Microsoft Remote SSH installed. You can connect through the Toolkit for Visual Studio Code extension in VS Code by browsing available SageMaker Unified Studio spaces and selecting their target environment.
SageMaker Unified Studio – Part of the next generation of Amazon SageMaker, SageMaker Unified Studio is a single data and AI development where you can find and access your data and act on it using familiar AWS tools for SQL analytics, data processing, model development, and generative AI application development.
AWS Systems Manager – A secure, scalable remote access and management service that enables seamless connectivity between your local VS Code and SageMaker Unified Studio spaces to streamline data and AI development workflows.
The following diagram shows the interaction between your local IDE and SageMaker Unified Studio spaces.
Prerequisites
To try the remote IDE connection, you must have the following prerequisites:
Access to a SageMaker Unified Studio domain with connectivity to the internet. For domains set up in virtual private cloud (VPC)-only mode, your domain should have a route out to the internet through a proxy or a NAT gateway. If your domain is completely isolated from the internet, refer to the documentation for setting up the remote connection. If you don’t have a SageMaker Unified Studio domain, you can create one using the quick setup or manual setup option.
Access to or can create a SageMaker Unified Studio project.
A JupyterLab or Code Editor compute space with a minimum instance type requirement of 8 GB of memory. In this post, we use an ml.t3.large instance. SageMaker Distribution image version 2.8 or later is supported.
You have the latest stable VS Code with Microsoft Remote SSH (version 0.74.0 or later), and AWS Toolkit (version 3.74.0) extension installed on your local machine.
Solution implementation
To enable remote connectivity and connect to the space from VS Code, complete the following steps. To connect to a SageMaker Unified Studio space remotely, the space must have remote access enabled.
Navigate to your JupyterLab or Code Editor space. If it’s running, stop the space and choose Configure space to enable remote access, as shown in the following screenshot.
Turn on Remote access to enable the feature and choose Save and restart, as shown in the following screenshot.
Navigate to AWS Toolkit in your local VS Code installation.
On the SageMaker Unified Studio tab, choose Sign in to get started and provide your SageMaker Unified Studio domain URL, that is, https://<domain-id>.sagemaker.<region>.on.aws.
You will be prompted to be redirected to your web browser to allow access to AWS IDE extensions. Choose Open to open a new web browser tab.
Choose Allow access to connect to the project through VS Code.
You’ll receive a Request approved notification, indicating that you now have permissions to access the domain remotely.
You can now navigate back to your local VS Code to access your project to continue building ETL jobs and data pipelines, training and deploying ML models, or building generative AI applications. To connect to the project for data processing and ML development, follow these steps:
Choose Select a project to view your data and compute resources. All projects in the domain are listed, but you’re only allowed access to projects where you’re a project member.
You can only view one domain and one project at a time. To switch projects or sign out of a domain, choose the ellipsis icon.
You can also view compute and data resources that you created previously.
Connect your JupyterLab or Code Editor space by selecting the connectivity icon, as shown in the following image. Note: If this option does not show as available, then you may have remote access disabled in the space. If the space is in “Stopped” state, hover over the space and choose the connect button. This should enable remote access, start the space and connect to it. If the space is in “Running” state, the space must be restarted with remote access enabled. You can do this by stopping the space and connecting to it as shown below from the toolkit.
Another VS Code window will open that is connected to your SageMaker Unified Studio space using remote SSH.
Navigate to the Explorer to view your space’s notebooks, files, and scripts. From the AWS Toolkit, you can also view your data sources.
Use your custom VS Code setup with SageMaker Unified Studio resources
When you connect VS Code to SageMaker Unified Studio, you keep all your personal shortcuts and customizations. For example, if you use code snippets to quickly insert common analytics and ML code patterns, these continue to work with SageMaker Unified Studio managed infrastructure.
In the following graphic, we demonstrate using analytics workflow shortcuts. The “show-databases” code snippet queries Athena to show available databases, “show-glue-tables” lists tables in AWS Glue Data Catalog, and “query-ecommerce” retrieves data using Spark SQL for analysis.
You can also use shortcuts to automate building and training an ML model on SageMaker AI. In the below graphic, the code snippets show data processing, configuring, and launching a SageMaker AI training job. This approach demonstrates how data practitioners can maintain their familiar development setup while using managed data and AI resources in SageMaker Unified Studio.
Disabling remote access in SageMaker Unified Studio
As an administrator, if you want to disable this feature for your users, you can enforce it by adding the following policy to your project’s IAM role:
SageMaker Unified Studio by default shuts down idle resources such as JupyterLab and Code Editor spaces after 1 hour. If you’ve created a SageMaker Unified Studio domain for the purposes of this post, remember to delete the domain.
Conclusion
Connecting directly to Amazon SageMaker Unified Studio from your local IDE reduces the friction of moving between local development and scalable data and AI infrastructure. By maintaining your personalized IDE configurations, this reduces the need to adapt between different development environments. Whether you’re processing large datasets, training foundation models (FMs), or building generative AI applications, you can now work from your local setup while accessing the capabilities of SageMaker Unified Studio. Get started today by connecting your local IDE to SageMaker Unified Studio to streamline your data processing workflows and accelerate your ML model development.
Amazon Web Services (AWS) is announcing the availability of universal macOS installers for the AWS Command Line Interface (AWS CLI) v2.
What’s new
Starting with AWS CLI v2 version 2.30.0, the AWS CLI installers will provide universal binary support for macOS that works natively on both Apple silicon and Intel processors with a single download. This eliminates the need for Rosetta translation, a compatibility layer that enables Intel-based applications to run on Apple silicon Macs.
Updating existing AWS CLI installations
If you’re using AWS CLI v2 on an Apple-silicon Mac, we recommend you upgrade to the latest version to install native binaries.
These changes only affect the official AWS CLI installers—building the AWS CLI from source will continue to natively support the host architecture.
When building serverless applications, developers typically focus on three key areas to streamline their testing experience: unit testing, integration testing, and debugging resources running in the cloud. Although AWS Serverless Application Model Command Line Interface (AWS SAM CLI) provides excellent local unit testing capabilities for individual Lambda functions, developers working with event-driven architectures that involve multiple AWS services, such as Amazon Simple Queue Service (Amazon SQS), Amazon EventBridge, and Amazon DynamoDB, need a comprehensive solution for local integration testing. Although LocalStack provided local emulation of AWS services, developers had to previously manage it as a standalone tool, requiring complex configuration and frequent context switching between multiple interfaces, which slowed down the development cycle.
LocalStack integration in AWS Toolkit for VS Code To address these challenges, we’re introducing LocalStack integration so developers can connect AWS Toolkit for VS Code directly to LocalStack endpoints. With this integration, developers can test and debug serverless applications without switching between tools or managing complex LocalStack setups. Developers can now emulate end-to-end event-driven workflows involving services such as Lambda, Amazon SQS, and EventBridge locally, without needing to manage multiple tools, perform complex endpoint configurations, or deal with service boundary issues that previously required connecting to cloud resources.
The key benefit of this integration is that AWS Toolkit for VS Code can now connect to custom endpoints such as LocalStack, something that wasn’t possible before. Previously, to point AWS Toolkit for VS Code to their LocalStack environment, developers had to perform manual configuration and context switching between tools.
Getting started with LocalStack in VS Code is straightforward. Developers can begin with the LocalStack Free version, which provides local emulation for core AWS services ideal for early-stage development and testing. Using the guided application walkthrough in VS Code, developers can install LocalStack directly from the toolkit interface, which automatically installs the LocalStack extension and guides them through the setup process. When it’s configured, developers can deploy serverless applications directly to the emulated environment and test their functions locally, all without leaving their IDE.
Let’s try it out First, I’ll update my copy of the AWS Toolkit for VS Code to the latest version. Once, I’ve done this, I can see a new option when I go to Application Builder and click on Walkthrough of Application Builder. This allows me to install LocalStack with a single click.
Once I’ve completed the setup for LocalStack, I can start it up from the status bar and then I’ll be able to select LocalStack from the list of my configured AWS profiles. In this illustration, I am using Application Composer to build a simple serverless architecture using Amazon API Gateway, Lambda, and DynamoDB. Normally, I’d deploy this to AWS using AWS SAM. In this case, I’m going to use the same AWS SAM command to deploy my stack locally.
I just do `sam deploy –guided –profile localstack` from the command line and follow the usual prompts. Deploying to LocalStack using AWS SAM CLI provides the exact same experience I’m used to when deploying to AWS. In the screenshot below, I can see the standard output from AWS SAM, as well as my new LocalStack resources listed in the AWS Toolkit Explorer.
I can even go in to a Lambda function and edit the function code I’ve deployed locally!
Over on the LocalStack website, I can login and take a look at all the resources I have running locally. In the screenshot below, you can see the local DynamoDB table I just deployed.
Enhanced development workflow These new capabilities complement our recently launched console-to-IDE integration and remote debugging features, creating a comprehensive development experience that addresses different testing needs throughout the development lifecycle. AWS SAM CLI provides excellent local testing for individual Lambda functions, handling unit testing scenarios effectively. For integration testing, the LocalStack integration enables testing of multiservice workflows locally without the complexity of AWS Identity and Access Management (IAM) permissions, Amazon Virtual Private Cloud (Amazon VPC) configurations, or service boundary issues that can slow down development velocity.
When developers need to test using AWS services in development environments, they can use our remote debugging capabilities, which provide full access to Amazon VPC resources and IAM roles. This tiered approach frees up developers to focus on business logic during early development phases using LocalStack, then seamlessly transition to cloud-based testing when they need to validate against AWS service behaviors and configurations. The integration eliminates the need to switch between multiple tools and environments, so developers can identify and fix issues faster while maintaining the flexibility to choose the right testing approach for their specific needs.
Now available You can start using these new features through the AWS Toolkit for VS Code by updating to v3.74.0. The LocalStack integration is available in all commercial AWS Regions except AWS GovCloud (US) Regions. To learn more, visit the AWS Toolkit for VS Code and Lambda documentation.
For developers who need broader service coverage or advanced capabilities, LocalStack offers additional tiers with expanded features. There are no additional costs from AWS for using this integration.
These enhancements represent another significant step forward in our ongoing commitment to simplifying the serverless development experience. Over the past year, we’ve focused on making VS Code the tool of choice for serverless developers, and this LocalStack integration continues that journey by providing tools for developers to build and test serverless applications more efficiently than ever before.
Today, we announce the availability of a Security Technical Implementation Guide (STIG) for Amazon Linux 2023 (AL2023), developed through collaboration between Amazon Web Services (AWS) and the Defense Information Systems Agency (DISA). The STIG guidelines are important for U.S Department of Defense (DOD) and Federal customers needing strict security compliance derived from the National Institute of Standards and Technology (NIST) 800-53 and related documents. This new technical implementation guide provides detailed Operating System (OS) security hardening configurations for organizations deploying AL2023 in DOD environments and other agencies requiring DISA STIG alignment. The AL2023 STIG provides customers with access to an OS guide that complies with stringent government security standards. This guide for implementing STIG configurations will streamline security processes for organizations seeking robust cybersecurity controls, whether they are needed to maintain DOD compliance or voluntarily adopting these best security practices to enhance their security posture.
Implementing the AL2023 DISA STIG with AWS
AWS Systems Manager (SSM) and EC2 Image builder offer native solutions for implementing the AL2023 DISA STIG configurations in your environment. For customers with existing AL2023 EC2 workload, they can utilize AWS Systems Manger (SSM) to streamline the STIG implementation. For customers who would like to build STIG compliant AL2023 EC2 instances to use for deployment, they can utilize EC2 Image Builder and automate the application of the AL2023 DISA STIG.
Customers can utilize EC2 Image builder to enhance and streamline their implementation of the AL2023 DISA STIG. This integrated approach significantly reduces the operational overhead traditionally associated with maintaining STIG compliance. Therefore, our customers can focus on their core missions while maintaining the highest security standards. Our customers can use AWS EC2 Image Builder’s existing Linux hardening components, which now support AL2023 Category I, II, and III findings to automatically create STIG-compliant AL2023 EC2 images with minimal manual intervention. This automation significantly reduces the time and effort typically needed for security hardening implementations. The EC2 Image Builder Linux hardening component extends its proven capabilities to AL2023, providing the same streamlined security configuration process available for other Linux distributions. For more information, refer to the Image Builder documentation.
Automating the STIG for Existing Fleets via Systems Manager
For existing AL2023 EC2 instances, you can use AWS-managed SSM command documents to automate the implementation of the STIG configurations. . These command documents can be executed through the SSM console, API, or AWS Command Line Interface (AWS CLI). The key mechanism here is the AWS managed Systems Manager command document, which contains the pre-defined STIG configurations. By leveraging these command documents through Systems Manager execution capabilities, customers can systematically deploy and maintain AL2023 STIG configurations across their fleet of EC2 instances. This generates consistent security baselines that meet government and enterprise requirements. This solution is particularly effective for environments with existing AL2023 EC2 instances as it allows customers to implement STIG controls without rebuilding or redeploying instances. For more information about the command document, refer to Apply STIG settings with Systems Manager in the EC2 User Guide.
The AL2023 STIG represents the continued commitment of Amazon Linux to providing customers with the security tools and guidance they need to succeed in highly regulated environments. Amazon Linux, in collaboration with DISA is providing their customers with access to authoritative, government-validated security configurations that meet the most demanding compliance requirements.
Ready to implement AL2023 STIG in your environment? Explore our comprehensive documentation and begin streamlining your security compliance journey today. To learn more about STIG hardening for your EC2 instances, refer to STIG compliance for your EC2 instance and for STIG settings that are applied to EC2 Linux instances, refer to the STIG settings for EC2 Linux instances. To apply STIG settings to your AL 2023 EC2 instance, download the AL2023 DISA STIG.
Amazon Q Developer provides generative AI assistance within Amazon SageMaker Unified Studio for data discovery, data processing, SQL analytics, and machine learning workflows. Today, we are announcing improvements to the Amazon Q Developer chat experience in SageMaker Unified Studio JupyterLab integrated development environment (IDE) and adding Amazon Q Developer in the command line in JupyterLab and Code Editor IDEs. By integrating with Model Context Protocol (MCP) servers, Amazon Q Developer is aware of your SageMaker Unified Studio project resources, including data, compute, and code, and provides personalized, relevant responses for data engineering and machine learning development. You can use this improved AI assistance to setup your development environment more quickly, and for tasks like code refactoring, file modification, and troubleshooting while maintaining transparency into how the AI assistant is acting on your behalf.
Solution implementation
In this post, we will walk through how you can use the improved Amazon Q Developer chat and the new built-in Amazon Q Developer CLI in SageMaker Unified Studio for coding ETL tasks, to fix code errors, and generate ML development workflows. Both interfaces use MCP to read files, run commands, and interact with AWS services directly from the IDE. You can also configure additional MCP servers to extend Amazon Q Developer’s capabilities with custom tools and integrations specific to your workflow.
Prerequisites
Before starting this tutorial, you must have the following prerequisites:
Access to a SageMaker Unified Studio domain. If you don’t have a Unified Studio domain, you can create one using the quick setup or manual setup option.
Access to or can create a JupyterLab or Code Editor compute space. We will walk through a JupyterLab IDE example. There is no minimum instance type requirement to use the new features. In this post, we use an ml.t3.medium instance. At launch, SageMaker Distribution images 2.9 (contains Amazon Q Developer chat and Amazon Q Developer CLI) or 3.4 (contains Amazon Q Developer CLI) are required.
Uploading the dataset to an Amazon S3 bucket
Download the Diabetes 130-US hospitals dataset. This dataset contains 10 years (1999–2008) of clinical care data from 130 US hospitals and integrated delivery networks.
On the Data section in the middle of your project page, choose + on the top. This opens Add data on the right.
On Add data, choose Create table.
Select Choose file or drag and drop the diabetic_data CSV file.
Select S3/external table and complete the information in the form.
Select Next to upload the dataset.
Amazon Q Developer chat
Amazon Q Developer chat in SageMaker Unified Studio is an agentic AI assistant that automatically understands your project, including data, compute resources, and code to provide highly relevant suggestions and insights. It helps you answer questions about your project, understand complex datasets, write code, and create notebooks, making it a powerful coding companion for creating ETL workflows, building ML models, or developing generative AI applications. We will walk through user personas, data engineer and ML engineer, to show how to use the Amazon Q Developer chat to do exploratory data analysis, troubleshoot code, and perform predictive analysis. Note: Amazon Q Developer code security scanning will auto-scan the code as it is being written in the IDE and provide recommendations for remediation and in some cases a code fix as well. This helps you proactively identify and remove security vulnerabilities in your codebase, both in existing codebase and in new code as you write it in the IDE.
To launch Amazon Q Developer chat:
Navigate to your project. Access the JupyterLab IDE. At the time of launch, Amazon Q Developer chat is only available in the JupyterLab IDE.
Choose the icon on the left for Amazon Q Developer chat. If this is the first time opening, a message displays for you to acknowledge the AWS policies for responsible AI.
Enter the questions to interact with Amazon Q Developer chat. Enter over the Ask a question… line.
The following are the steps to configure additional MCP servers:
Navigate to Amazon Q Developer chat and select the Configure MCP servers tools icon in the upper right. You also have the option edit the configuration file located at /home/sagemaker-user/.aws/amazonq/agents/default.json to add an MCP sever in Amazon Q Developer chat. You can also navigate to /home/sagemaker-user/.aws/amazonq/mcp.json in the terminal and edit the configuration file to add an MCP server in Amazon Q Developer CLI.
Select the + symbol to Add new MCP server.
Add the following information in the form:
Select the scope: Global
Name: Enter awsdp-mcp
Transport: Select stdio
Command: Enteruvx
Arguments-optional: Enter awslabs.aws-dataprocessing-mcp-server@latest
Choose Save.
Data engineer
As a data engineer, you might build ETL jobs and data pipelines. Amazon Q Developer chat helps reduce setup time and improves workflow efficiency by refactoring code, implementing best practices, and troubleshooting errors. Amazon Q Developer uses AI to provide code recommendations, and this is non-deterministic. The results you get might be different from the ones shown in the following examples. Example prompt:
You are a data engineer. Your responsibility is to perform descriptive and exploratory data analysis.
* Use the diabetic_data dataset in SageMaker Lakehouse.
* Find list of connections and note down their names
* Create a notebook. Use getting_started.ipynb for best practices and as an example notebook.
* Make sure to use correct connection names in cell magic commands
* Make sure to handle missing values, perform descriptive analysis, and feature analysis.
* Create a comprehensive README.md file.
* Create a new working directory under the /src directory.
Run the following steps, after the solution is created.
Go to the notebook.
Run the created notebook and review each section:
Data loading
Descriptive analysis
Correlation matrix
Data preprocessing such as handling missing values
Analyze importance of features
Review the README.md file.
You can make changes on the created files.
You can prompt the Amazon Q Developer chat to make additional changes for you.
Fix errors without specifying the error
You can give instructions in a conversational way to Amazon Q Developer chat. Without the need to specify the error, Amazon Q Developer chat will access your notebook and fix the error.
Open your notebook.
Prompt The notebook isn’t running, can you fix it? Amazon Q Developer chat will identify the error from the notebook.
Review the issue and the solution. Run the notebook again.
ML engineer
As an ML engineer, you might analyze complex datasets and run ML experiments. You can ask Amazon Q Developer chat to take on an ML engineer role and perform a predictive ML model on the dataset. Also, you can ask to take the output from the data engineer into account. Example prompt:
You are a machine learning engineer. Your responsibility is to perform predictive machine learning model on the data. The data engineer performed exploratory analysis. Use the output from the data engineer in your notebook.
- Create a notebook to build a diabetes prediction model using Amazon SageMaker.
- Make sure to have model evaluation.
- Explain your choice for features and model selection.
- Create a comprehensive README.md file
- Do this in the working directory you created
Run the following steps, after the solution is created:
Run the created notebook and review each section:
Note that the notebook is running successfully.
Amazon Q chat incorporated feature engineering section based on data engineer’s output.
Four ML models (Logistic Regression, Random Forest, Gradient Boosting, and XGBoost) were identified for diabetes readmission prediction.
Models were evaluated using a comprehensive metrics suite including accuracy, precision, recall, F1 score, and ROC AUC to help ensure balanced performance.
Feature engineering produced critical predictors such as previous inpatient visits and medication changes, while hyperparameter tuning optimized model performance.
The final implementation balances predictive power with clinical interpretability, enabling effective identification of high-risk patients.
Amazon Q Developer CLI
The Amazon Q Developer CLI also understands your code, data, and compute resources, but is optimized for users who prefer working in the terminal. It helps you execute and automate data processing, model training, and generative AI tasks through natural language prompts.To launch the Amazon Q Developer CLI:
On the top menu of your SageMaker Unified Studio project page, choose Build, and under IDE & APPLICATIONS, choose JupyterLab.
Wait for the space to be ready.
From the Launcher tab, open a new terminal. Or navigate to File > New > Terminal.
Enter q chat
At launch, Anthropic’s Claude Sonnet 4 in Amazon Bedrock is the default large language model (LLM). You can choose other LLMs, depending on your AWS Region. To view the available models or change the models enter /model. MCP tools are executable functions that MCP servers expose to the Amazon Q Developer CLI. They enable Amazon Q Developer to perform actions, process data, and interact with external systems on your behalf. To view the available tools, enter /tools.
Example prompt:
Explore the datasets available in the project’s data catalog and do exploratory analysis.
Clean up
SageMaker Unified Studio by default shuts down idle resources such as JupyterLab and Code Editor spaces after 1 hour. However, you need to delete the Amazon Simple Storage Service (Amazon S3) bucket to stop incurring additional charges. You can delete any real-time endpoints you created using the SageMaker console. For instructions, see Delete Endpoints and Resources.
Conclusion
The improved AI assistance available in JupyterLab and Code Editor IDEs in SageMaker Unified Studio helps streamline data engineering and machine learning workflows by providing answers relevant to your project files, notebooks, data, and compute. Whether you’re a data engineer building ETL pipelines, a data scientist conducting exploratory analysis, or an ML engineer developing predictive models, these features now understand what you’re working on and help you do it more efficiently. This is just the start of our agentic journey in SageMaker Unified Studio. To learn more, review the SageMaker Unified Studio User Guide. We encourage you to explore the MCP capabilities and the AWS MCP Servers repository on GitHub.
About the authors
Lauren Mullennex is a Senior GenAI/ML Specialist Solutions Architect at AWS. She has over a decade of experience in ML, DevOps, and infrastructure. She is a published author of a book on computer vision. Outside of work, you can find her traveling and hiking with her two dogs.
Siddharth Gupta is heading Generative AI within SageMaker’s Unified Experiences. His focus is on driving agentic experiences, where AI systems act autonomously on behalf of users to accomplish complex tasks. Previously, he led edge machine learning solutions at AWS. This cutting-edge work aims to revolutionize how developers and data scientists interact with AI, creating more intuitive data integrations and powerful tools for building and deploying machine learning models. An alumnus of the University of Illinois at Urbana-Champaign, he brings extensive experience from his roles at Yahoo, Glassdoor, and Twitch. You can reach out to him on LinkedIn.
Ishneet Kaur is a Software Development Manager on the Amazon SageMaker Unified Studio team. She leads the engineering team to design and build GenAI capabilities in SageMaker Unified Studio
Mohan Gandhi is a Senior Software Engineer at AWS. He has been with AWS for the last 10 years and has worked on various AWS services like Amazon EMR, Amazon EFA, and Amazon RDS. Currently, he is focused on improving the SageMaker inference experience. In his spare time, he enjoys hiking and marathons.
Mukul Prasad is a Senior Applied Science Manager in the AWS Agentic AI organization. He leads the Data Processing Agents Science team developing DevOps agents to simplify and optimize the customer journey in using AWS Big Data processing services including Amazon EMR, AWS Glue, and Amazon SageMaker Unified Studio. Outside of work, Mukul enjoys food, travel, photography, and Cricket.
Murali Narayanaswamy is a Principal Machine Learning Scientist in the Agentic AI organization in AWS working on products including Amazon Bedrock, Amazon SageMaker Unified Studio, Amazon Redshift and Amazon RDS. His research interests lie at the intersection of AI, optimization, learning and inference particularly using them to understand, model and combat noise and uncertainty in real world applications and Reinforcement Learning in practice and at scale. Broadly, he works on using ideas from online algorithms, optimization under uncertainty, control theory, game theory, artificial intelligence, graphical models and estimation theory to solve important problems at Amazon scale.
Necibe Ahat is a Senior AI/ML Specialist Solutions Architect at AWS, working with Healthcare and Life Sciences customers. Necibe helps customers to advance their generative AI and machine learning journey. She has a background in computer science with 15 years of industry experience helping customers ideate, design, build and deploy solutions at scale. She is a passionate inclusion and diversity advocate.
Vipin Mohan is a Principal Product Manager at Amazon Web Services, where he leads generative AI product strategy. He specializes in building AI/ML products, container platforms, and search technologies that serve thousands of customers. Outside of work, he mentors aspiring product managers, enjoys reading about financial investing and entrepreneurship, and loves exploring the world through the eyes of his two kids.
Code reviews are one of the most valuable rituals in software development. They help ensure quality, maintain consistency, and foster growth as engineers. But they’re also one of the most time consuming steps in the software development lifecycle. A common pattern I’ve seen is a developer opening a pull request (PR), receiving automated or peer comments, and then needing to search through documentation, Slack threads, or past code just to understand why a change was suggested. That search for missing context creates a friction that slows teams down, adds back-and-forth cycles, and often distracts from the bigger picture of building great products.
In the initial preview experience, teams used Amazon Q Developer in GitHub across issues and PRs for feature work, automated code reviews, and common modernization tasks. This kept work inside GitHub and reduced handoffs. Automatic reviews on new or reopened PRs surfaced findings early, but teams still wanted more context and a tighter loop inside the PR.
Today we’re introducing an interactive code review experience for PRs You can ask Amazon Q Developer questions about any finding using /q, see a concise summary with threaded findings, and apply suggested changes without leaving GitHub. Code reviews by Amazon Q Developer now complete quicker than before, which reduces wait time and shortens the review cycle so teams can merge sooner and spend more time building.
What’s new and why it matters
Interactive Conversations in the pull request: Comment with /q to get inline answers, or ask Q Developer to propose a code change you can apply in the PR. For example:/q explain this finding or /q propose a change that replaces class toggles with a data attribute for state.
Code review summaries with threaded findings: Each code review begins with a concise summary and findings are threaded underneath. This makes updates easier to follow and reduces noise.
Faster execution with clearer notifications: Amazon Q Developer completes its analysis quicker and notifications are organized and easier to scan. This reduces wait time and shortens the review cycle. When you create or open a new PR, Amazon Q Developer automatically starts a code review if the code review feature is enabled for your GitHub installation in the Amazon Q Developer console. Subsequent commits do not trigger another automatic review. To run a fresh analysis, post /q review as a new comment on the PR.
Getting Started with Amazon Q Developer in GitHub
To get started, install the Amazon Q Developer GitHub App in your GitHub organization or repository. The app is available through the GitHub Marketplace and can be used without an AWS account during the preview. During installation, you choose whether to provide access to all repositories or only selected repositories in your GitHub organization. You can increase free usage by registering the app installation in the Amazon Q Developer console. For more details on installation, permissions, and configuration options, see the Amazon Q Developer for GitHub documentation. Once the app is installed, you can begin using Q Developer to review PRs automatically.
Using Amazon Q Developer in Pull Requests
To dive deeper, here’s an end-to-end walk-through of the new interactive code review experience using a simple card game I built with Amazon Q Developer.
Create a new pull request : In this example, I started by creating a feature branch and named it demo, added atailwind.css file to the JavaScript and HTML card game app, pushed the branch, and opened a PR for review.
Amazon Q Developer automaticallystarts a code review, analyzing code quality, potential issues, and adherence to best practices. A concise summary appeared at the top, with individual findings threaded underneath. This gave me the big picture and the specifics in one place.
Code review the summary and findings: I reviewed the summary and threaded findings to decide which change to take on first. Seeing both the rationale and the exact lines called out meant I knew where to begin, without hunting through files.
Ask for Clarification with /q : One of the findings suggested using state property to track the card status in my card game application. so I asked Q Developer for clarification. It responded quickly with concrete context and pointers, which reduced back and forth and improved the quality of the review.
Continue the conversation (if needed) : I reviewed Q Developer’s suggestion and responded back stating that I preferred an alternate approach and Q Developer quickly returned a complete implementation I could apply in the PR
Apply Fixes : After reviewing the implementation suggestion, I clicked on Commit suggestion to create a new commit on the PR branch with my username as the author.
Re-run the review : I didn’t need this for my example, but if you push additional changes, you can run a fresh analysis by posting /q review as a new top-level comment. Q Developer will run the review and post updated findings.
With the code review complete and checks passing, I merged. The new interactive code review experience reduced wait time and review cycles and made the “why” behind each finding and suggested change clear.
Conclusion
Amazon Q Developer for GitHub is available today in preview. Whether you are an individual developer or part of a large engineering team, this update helps you ship cleaner code with fewer cycles and makes code reviews something to look forward to rather than avoid. Try it out on your next PR. Type /q, ask a question, and see how smarter conversational reviews transform your workflow.
Security and compliance concerns are key considerations when customers across industries rely on Amazon SageMaker Catalog. Customers use SageMaker Catalog to organize, discover, and govern data and machine learning (ML) assets. A common request from domain administrators is the ability to enforce governance controls on certain metadata terms that carry compliance or policy significance. Examples include terms used to classify assets with sensitive data (such as PHI in healthcare or PCI in financial services) or terms used to trigger automatic access grants based on regulatory or organizational policies.
AWS announced restricted classification terms in SageMaker Catalog. This new capability allows domain administrators to define governance-controlled terms and enforce which teams and users are authorized to apply them. Restricted classification terms are designed to allow organizations to set standards for consistent classification of sensitive data, help prevent misuse of regulatory tags, and enable downstream workflows such as automatic access grants across the enterprise.
Restricted classification (glossary) terms
Customers have told us that the flexibility of applying glossary terms in SageMaker Catalog has been valuable for collaboration and scale. At the same time, many enterprises—especially in regulated industries—wanted an additional layer of control for certain classifications. For example, terms like PHI (Protected Health Information) in healthcare or PCI (payment card industry) in financial services should only be applied by authorized personnel, because they carry compliance and policy significance. Customers also asked for a way to enforce these governance policies without adding operational overhead. As catalogs grow to thousands of assets, forms, and columns, validating tens of thousands of terms can create performance and compliance challenges. A solution was needed to combine the openness of cataloging with governance precision for sensitive use cases.With this launch, SageMaker Catalog introduces a restricted classification terms section on each asset:
Business glossary terms (existing): Open tagging, no restrictions.
Restricted glossary terms (new): Only authorized users or groups can apply terms. Unauthorized users can view and filter assets based on these terms but not assign them.
Customer spotlight
As a large-scale organization with diverse data needs, the Business Data Technologies (BDT) team at Amazon manages thousands of assets across business units. Making sure these assets are consistently classified and governed is critical to maintaining compliance and enabling secure data sharing at scale. With restricted classification terms in SageMaker Catalog, the BDT team can now enforce which groups are authorized to apply terms, such as policy-driven classifications for merchants or payment data, while keeping discovery seamless for users.
“Restricted classification terms are instrumental in helping us scale data onboarding and governance across Amazon. By enforcing who can apply policy-related terms in the Amazon SageMaker Catalog, we’re able to accelerate consolidation of data assets across business units without compromising compliance. This facilitates consistent classification, prevents misuse, and allows us to automate downstream access grants—enabling our builders to innovate quickly while maintaining the highest standards of governance.”
– Gerry Moses, Senior Principal Technologist, Business Data Technologies, Amazon
Key benefits
With the introduction of restricted classification terms, customers gain stronger governance controls without losing the flexibility of open cataloging. This capability is designed to provide customers with the following key benefits:
Governance enforcement – Sensitive terms such as PHI or PCI can only be applied by approved users or groups, supporting compliance with organizational and regulatory policies.
Consistency at scale – Helps prevent misclassification across thousands of assets, maintaining a single source of truth for governed terms across domains and projects.
Automatic access workflows – Restricted terms can trigger downstream policies, such as auto-granting access to regulated projects or routing assets to compliance-approved environments.
Sample use case
A pharmaceutical company uses SageMaker Catalog to manage clinical trial data. They define a glossary called Regulated Data Categories with restricted terms like PHI and Genomic Data. Only compliance-approved data stewards are authorized to apply these terms to assets. When applied, the term PHI can automatically trigger policies that restrict access only to approved research groups or environments with HIPAA compliance enabled. This makes sure clinical datasets containing PHI to be consistently tagged and subject to the right access policies, while still discoverable for approved researchers.
A retail bank manages transaction and credit data in its domain catalog. They create a glossary called Data Sensitivity Levels with restricted terms like PCI and Credit Bureau Data. When an authorized risk officer classifies an asset with PCI, SageMaker Catalog can automatically grant access only to members of the bank’s Payments Compliance project. Other users, such as analysts in marketing, can see the classification exists but cannot apply or override it. This approach helps prevent accidental misuse of sensitive financial terms while automating secure access grants aligned with regulatory requirements.
Solution overview
In this section, we will walk through how to create and apply restricted classification terms.
Prerequisites
To follow this post, you should have an Amazon SageMaker Unified Studio domain set up with a domain owner or domain unit owner privileges. You should also have existing projects or permissions to create new projects and business glossaries. For instructions to create them, see the Getting started guide. In this post, we created a project named Clinical Study Trials.
Create a restricted business glossary
In this step, a compliance officer creates a new glossary called Regulated Data Categories and marks it as restricted. Usage grants are given to the Clinical Data Stewardship project.
Log in to your Amazon SageMaker Unified Studio (off-console) portal. Select the project, navigate to Business Glossaries tab and choose Create Glossary.
Enter a name and description for the glossary. Select Restrict this glossary for governed term use and choose Add projects.
Select the projects that should have permissions to tag governed terms to assets. Choose Add policy grant.
Choose Create to create the restricted business glossary.
The Regulated Data Categories business glossary is created and ready to populate.
Add restricted business glossary terms
In this step you will add two terms: PHI and Genomic Data to the glossary.
Choose Create term.
Enter a Name and Description. Turn on Enabled and choose Create term.
Follow the same steps to add the second term and both terms should be available in the glossary.
Apply restricted glossary terms to classify assets
In this step, a data steward will publish a new asset and apply the restricted terms.
Go to the Data Steward project and navigate to the asset where Restricted Terms should be tagged and choose Add terms.
From Regulated Data Categories select PHI and Genomic Data and choose Add terms.
Restricted terms are attached to the asset.
If a project that doesn’t have grants to use restricted term tries to attach restricted terms, you would receive the error Unable to apply restricted terms.
Search and discovery
Data consumers can search for assets and filter by restricted terms filters on the left filters tab (for example, PHI or PCI) to discover governed assets.
As customers expand their use of SageMaker Catalog, the need for governance becomes clear. From our work with customers in healthcare, life sciences, and financial services, we learned that organizations value the flexibility of open cataloging but need precise controls for terms that carry compliance or policy weight.
Restricted classification terms are designed to bring the best of both worlds: Flexibility for builders to continue tagging and discovering assets, and governance precision to help ensure that sensitive classifications are applied consistently. This capability lays the foundation for future enhancements such as column-level governance and deeper integration with enterprise data governance services. By balancing openness with control, SageMaker Catalog continues to help customers organize, govern, and scale their data and ML assets with confidence.
In March 2025, AWS announced the general availability of the next generation of Amazon SageMaker, including Amazon SageMaker Unified Studio, a single data and AI development environment that brings together the functionality and tools from existing AWS Analytics and AI/ML services, including Amazon EMR, AWS Glue, Amazon Athena, Amazon Redshift, Amazon Bedrock, and Amazon SageMaker AI. You can discover data and AI assets from across your organization, then work together in projects to securely build and share analytics and AI artifacts, including data, models, and generative AI applications in a trusted and secure environment. Governance features including fine-grained access control are built into Amazon SageMaker Unified Studio using Amazon SageMaker Catalog to help you meet enterprise security requirements across your entire data estate. Unified access to your data is provided by a unified, open, and secure data lakehouse architecture built on Apache Iceberg open standards. Whether your data is stored in Amazon Simple Storage Service (Amazon S3) data lakes, Amazon Redshift data warehouses, or third-party and federated data sources, you can access it from one place and use it with Iceberg-compatible engines and tools.
AWS for Financial Services is a pioneer at the intersection of financial services and technology, enabling our customers to optimize operations and push the boundaries of innovation with the broadest set of services and partner solutions—all while maintaining security, compliance, and resilience at scale. Financial institutions are using AI and machine learning (ML), and generative AI services on AWS to transform their organizations faster and in ways never before possible. With Amazon SageMaker Unified Studio, financial services industry (FSI) customers can seamlessly work across different compute resources and clusters using unified notebooks, including generative AI–powered troubleshooting capabilities, and use the built-in SQL editor to query data stored in data lakes, data warehouses, databases, and applications.
Workshops
In this post, we’re excited to announce the release of four Amazon SageMaker Unified Studio publicly available workshops that are specific to each FSI segment: insurance, banking, capital markets, and payments. These workshops can help you learn how to deploy Amazon SageMaker Unified Studio effectively for business use cases. Follow the links for each FSI use case listed in the following table to get started for these self-paced workshops.
In this workshop, you’ll use Amazon SageMaker Unified Studio and analytics services to transform your insurance business challenges into opportunities. It provides hands-on experience in developing data-driven, generative AI–powered solutions for insurance that deliver measurable business value.
In this workshop, you’ll explore how leading retail banks can unlock business value by using Amazon SageMaker Unified Studio to build, scale, and govern end-to-end data analytics and ML workflows. The workshop walks you through a reference architecture and curated banking-specific datasets covering common retail banking use cases, such as customer segmentation, fraud detection, churn prediction, and generative AI applications like personalized communication.
In this workshop, you’ll use Amazon SageMaker Unified Studio to analyze trade and quote data for the S&P 500 stocks to generate insights. The data is stored in various formats across different sources. This solution will unify the data from disparate sources using a lakehouse architecture and offer team members flexibility to access the data using familiar SQL constructs.
In this workshop, you’ll use Amazon SageMaker Unified Studio and analytics services to enable organizations to ingest, store, process, and analyze payment data, supporting needs from data ingestion and storage to big data analytics, streaming analytics, business intelligence, and machine learning.
Conclusion
We appreciate your comments and feedback to help us accelerate adoption of Amazon SageMaker Unified Studio for financial services workloads. Contact your AWS account team to engage a FSI specialist solutions architect if you require additional expert guidance.
Learn more about AWS for financial services, customer case studies, and additional resources on our Financial Services website.
Efficiently integrating and analyzing Salesforce data is essential in today’s business environment. AWS GlueZero ETL (extract, transform, and load) now supports SalesforceBulk API, delivering substantial performance gains compared to Salesforce REST API for large-scale data integration for targets such as Amazon SageMaker lakehouse and Amazon Redshift. You can use this enhancement to process millions of Salesforce records in minutes while efficiently handling wide-column entities with hundreds of fields. In this blog post, we show you how to use Zero-ETL powered by AWS Glue with Salesforce Bulk API to accelerate your data integration processes.
Zero-ETL represents a modern approach to data integration that eliminates the need for traditional ETL processes by establishing direct connections between data sources and destinations. Rather than explicitly extracting data, transforming it, and loading it in separate steps, Zero-ETL handles these operations in the background. Zero-ETL enables direct integration with software as a service (SaaS) applications like Salesforce, automatically synchronizing data while maintaining consistency and eliminating the complexity of manual ETL pipeline development. This approach reduces development time, maintenance overhead, and the potential for errors in data movement processes.
Solution overview
Traditionally, Zero-ETL used Salesforce REST API for data ingestion. While the REST API provides a straightforward way to interact with Salesforce data, it comes with certain limitations, especially when dealing with large datasets. These include request limits, data volume constraints, performance overhead, and concurrency limitations. As of August 2025, depending on the Salesforce edition and license type, you might be limited to between 15,000 and 100,000 API calls per 24-hour period. When retrieving large volumes of data, multiple API calls are required, leading to inefficiency and extended processing times.
To address these limitations and enhance performance, AWS Glue Zero-ETL now supports Salesforce Bulk API. The Bulk API is designed for processing large datasets, offering several advantages over the REST API. It uses asynchronous processing, so you can process much larger data volumes without timing out. Data is processed in batches, which can be parallelized for faster processing. As of August 2025, the Bulk API also has more generous limits; up to 150,000,000 API calls, which is 15,000 batches, per 24-hour period, with each batch containing up to 10,000 records. The following diagram shows a Salesforce Zero-ETL architecture ingesting data through Salesforce Bulk and REST APIs and writing to Amazon SageMaker Lakehouse (in Amazon Simple Storage Service (Amazon S3) or Apache Iceberg) or Amazon Redshift.
The diagram illustrates the Zero-ETL data flow from Salesforce to AWS analytics services. Salesforce data is ingested using smart API processing, which intelligently selects between Bulk API for standard fields and REST API for compound fields. This approach is necessary because, as of now, the Salesforce Bulk API does not support compound fields (such as Address). Therefore, you must use the REST API in such cases for comprehensive data extraction. The solution supports Salesforce wide-column entities containing up to 800 fields, enabling comprehensive data integration. The processed data is then staged in an S3 bucket owned by the service team before being made available in the AWS Glue Data Catalog or Amazon Redshift, ready for analytics and machine learning applications.
AWS Glue Zero-ETL now uses the Salesforce Bulk API by default for most data integration scenarios, delivering superior performance and scalability. This approach optimizes data extraction for most use cases, particularly when dealing with large datasets. However, the solution automatically switches to the REST API when handling compound fields. Compound fields, such as addresses (which include street, city, state, postal code, and country), are automatically processed using the REST API.This intelligent API selection provides efficient processing while maintaining the performance benefits of the Bulk API for standard data extraction. This hybrid approach provides the best of both worlds: the scalability and throughput of the Bulk API for most operations, with the specialized handling capabilities of the REST API where it makes the most sense. The system handles this switch automatically, so you don’t need to worry about which API to use for different scenarios.
Performance details
After implementing Salesforce Bulk API support in AWS Glue Zero-ETL, you can see significant performance improvements that scale dramatically with data volume. To test performance benefits, we created a custom object in our Salesforce account and populated it with 10 million records. We then established a Zero-ETL integration between Salesforce and AWS Glue databases to measure data transfer performance. The most impressive gains are evident with large-scale operations: processing 10 million records now completes in 6 minutes and 20 seconds compared to 28 minutes and 53 seconds with the REST API—representing a 4.6-fold improvement in processing time in our controlled testing environment, as shown in the following figure. Performance improvements can vary depending on factors such as data volume, field complexity, network conditions, and computational resources.
Multi-entity processing scenarios, where four different Salesforce objects are processed simultaneously, demonstrate the solution’s scalability. Even with this concurrent load, 1 million records across multiple entities complete processing in under 3 minutes, showcasing the Bulk API’s superior handling of real-world data integration scenarios, as shown in the following figure.
This performance pattern demonstrates that the Bulk API’s asynchronous, batch-oriented architecture delivers exceptional results when handling the large-scale data volumes that enterprises typically encounter in production Salesforce integrations. The performance advantage scales directly with data volume, making it particularly valuable for organizations processing millions of records in their daily operations. As dataset size increases, the efficiency gains become increasingly pronounced, establishing the Bulk API as the optimal choice for enterprise-scale data processing requirements.Beyond the impressive performance gains with large datasets, our recent enhancements have also unlocked another critical capability: efficient processing of wide-column entities. Our performance benchmarks demonstrate this capability in action, with custom objects containing up to 800 columns and 226 KB record sizes processing in just 2 minutes and 11 seconds, while entities with 500 columns and 140 KB records complete in 2 minutes and 3 seconds, and 100-column entities with 28 KB records process in 1 minute and 56 seconds (shown in the following figure). This remarkable consistency across varying column counts and record sizes demonstrates that Zero-ETL from SaaS applications maintains excellent performance while efficiently ingesting and processing these wide-column entities, which means that you can use your complete Salesforce datasets for analytics and machine learning initiatives.
Impact
The performance improvements, demonstrated by AWS Glue Zero-ETL with Salesforce Bulk API support, offer tangible benefits for businesses managing large volumes of Salesforce data. As mentioned earlier, our controlled testing, demonstrated a 4.6-fold improvement over the REST API when processing 10 million records. With these results, you can significantly reduce your data integration time windows. This faster processing allows for more frequent data updates, potentially enabling you to work with fresher data for your analytics and reporting needs. Additionally, the efficient handling of wide-column entities, such as processing custom objects with up to 800 columns in just over 2 minutes, means that you can more readily use your complete Salesforce datasets without sacrificing performance.
Prerequisites
Before implementing this solution, you need to have the following in place:
A Salesforce Enterprise, Unlimited, or Performance Edition account
An AWS account with administrator access
Create an AWS Glue database with a name such as zero_etl_bulk_demo_db and associate the S3 bucket zeroetl-etl-bulk-demo-bucket as a location of the database.
Create an AWS Identity and Access Management (IAM) role named zero_etl_bulk_role. The IAM role will be used by Zero-ETL to access data from your Saleforce account
Create the secret zero_etl_bulk_demo_secret in AWS Secrets Manager to store Salesforce credentials.
Build and verify the zero-ETL integration
This section covers the steps required to set up a Salesforce connection and using that connection to create a Zero-ETL integration.
Step 1: Set up a connector to your Salesforce instance to enable data access
In the navigation pane, under Data catalog, choose Zero-ETL integrations.
Choose Create zero-ETL integration.
In the Create integration pane, enter Salesforce in Data Sources.
Choose Salesforce.
Choose Next.
Select the connection name that you created in the previous step.
Select the IAM role which you created in the previous step.
For Salesforce object, select the objects you want to perform the ingestion managed by Zero-ETL integration. For this post, select Opportunity.
For Namespace or Database In this example, we use the zero_etl_bulk_demo_db (from the prerequisites).
For Target IAM role, select the zero_etl_demo_role (from the prerequisites).
Choose Next.
In the Integration details section, for Name, enter zero-etl-bulk-demo-integration.
Choose Next.
Review the details and choose Create and launch integration.
The newly created integration will show as Active in about a minute.
Clean up
Note that following these steps will permanently delete the resources created in this post; back up any important data before proceeding.
Delete the Zero-ETL integration zero-etl-bulk-demo-integration.
Delete content from the S3 bucket zeroetl-etl-bulk-demo-bucket.
Delete the Data Catalog database zero_etl_bulk_demo_db.
Delete the Data Catalog connection zero_etl_bulk_demo_conn.
Delete the Secrets Manager secret zero_etl_bulk_demo_secret.
Conclusion
The integration of Salesforce Bulk API support in AWS Glue Zero-ETL marks a significant advancement in our data integration capabilities. By addressing the limitations of the REST API, efficiently handling wide-column entities and compound fields, and implementing robust error handling, you can now use AWS Glue Zero-ETL to ingest larger volumes of Salesforce data more efficiently.This enhancement improves performance and opens up new possibilities for your organization to use their Salesforce data for analytics, machine learning, and other data-driven initiatives. As we continue to evolve AWS Glue Zero-ETL, we remain committed to providing cutting-edge solutions that empower our customers to make the most of their data integration processes.
Summer has drawn to a close here in Utrecht, where I live in the Netherlands. In two weeks, I’ll be attending AWS Community Day 2025, hosted at the Kinepolis Jaarbeurs Utrecht on September 24. The single-day event will bring together over 500 cloud practitioners from across the Netherlands, featuring 25 breakout sessions across five technical tracks. The day will begin with virtual keynotes at 9:00 AM, followed by parallel breakout sessions focused on practical implementations of serverless architectures and container optimization strategies, providing valuable insights regardless of experience level.
Last year’s AWS Community Day Netherlands 2024 brought together a diverse group of cloud practitioners, speakers, and AWS enthusiasts who contributed to making the community-led conference a valuable knowledge-sharing platform. If you’re planning to attend, feel free to find me there to discuss AWS services or share your cloud implementation experiences!
Let’s look at last week’s new announcements.
Last week’s launches
AWS Transform assessments now includes detached storage analysis – AWS Transform has expanded its assessment capabilities to analyze on-premises detached storage infrastructure, helping customers determine migration total cost of ownership (TCO). The assessment now evaluates Storage Area Network (SAN), Network Attached Storage (NAS), file servers, object storage, and virtual environments, providing migration recommendations to appropriate AWS services including Amazon S3, Amazon EBS, and Amazon FSx. The tool delivers a comprehensive TCO comparison between current and AWS environments, along with performance and cost optimization recommendations. With storage accounting for up to 45% of total migration opportunities, this enhancement helps customers visualize various AWS migration options. AWS Transform assessment is available in US East (N. Virginia) and Europe (Frankfurt) Regions.
Amazon Bedrock introduces Global Cross-Region inference for Anthropic Claude Sonnet 4 – Anthropic’s Claude Sonnet 4 model in Amazon Bedrock now supports Global cross-Region inference, allowing inference requests to route to any supported commercial AWS Region for processing. This enhancement optimizes available resources and enables higher model throughput by distributing traffic across multiple Regions. Previously, you could select cross-Region inference profiles tied to specific geographies (US, EU, or APAC). The new Global cross-Region inference profile provides additional flexibility for generative AI use cases that don’t require geography-specific processing, helping manage unplanned traffic bursts and increase model throughput. For detailed implementation guidance, visit the Amazon Bedrock documentation.
Amazon Neptune Database adds Public Endpoints support – Amazon Neptune now supports Public Endpoints, enabling direct connections to Neptune databases from outside the VPC without complex networking configurations. This feature helps developers securely access their graph databases from development desktops without requiring VPN connections or bastion hosts, while maintaining security through IAM authentication, VPC security groups, and encryption in transit. Public Endpoints can be enabled for Neptune clusters running engine version 1.4.6 or above through the AWS Management Console, AWS CLI, or AWS SDK. The feature is available at no additional cost beyond standard Neptune pricing in all AWS Regions where Neptune Database is offered. Implementation details are available in the Amazon Neptune documentation.
ECS Exec now available in AWS Management Console – Amazon ECS now supports ECS Exec directly in the AWS Management Console, enabling secure, interactive shell access to running containers without requiring inbound ports or SSH key management. Previously available only through API, CLI, or SDKs, this feature streamlines troubleshooting by allowing container access directly from the console interface. You can enable ECS Exec when creating or updating services and standalone tasks, then connect to containers by selecting “Connect” on the task details page, which opens an interactive session through CloudShell. The console also displays the underlying AWS CLI command for use in local terminals. This feature is available in all AWS commercial Regions and documented in the ECS developer guide.
Organizational Notification Configurations for AWS User Notifications now generally available – AWS User Notifications now supports Organizational Notification Configurations, helping AWS Organizations users centrally configure and view notifications across their organization. Management accounts or delegated administrators can configure notifications for specific organizational units or all accounts in an organization. The service supports configuring notifications for any supported Amazon EventBridge event, such as console sign-ins without MFA, with notifications appearing in the admin’s Console Notifications Center and AWS Console Mobile Application. User Notifications supports up to five delegated administrators and is available in all AWS Regions where AWS User Notifications is offered. For implementation details, visit the AWS User Notifications user guide.
Upcoming AWS events Check your calendar and sign up for upcoming AWS events.
AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Zurich (September 11), Los Angeles (September 17), and Bogotá (October 9).
AWS re:Invent 2025 – Join us in Las Vegas between December 1–5 as cloud pioneers gather from across the globe for the latest AWS innovations, peer-to-peer learning, expert-led discussions, and invaluable networking opportunities. Don’t forget to explore the event catalog.
AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Baltic (September 10), Aotearoa (September 18), South Africa (September 20), Bolivia (September 20), Portugal (September 27).
This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
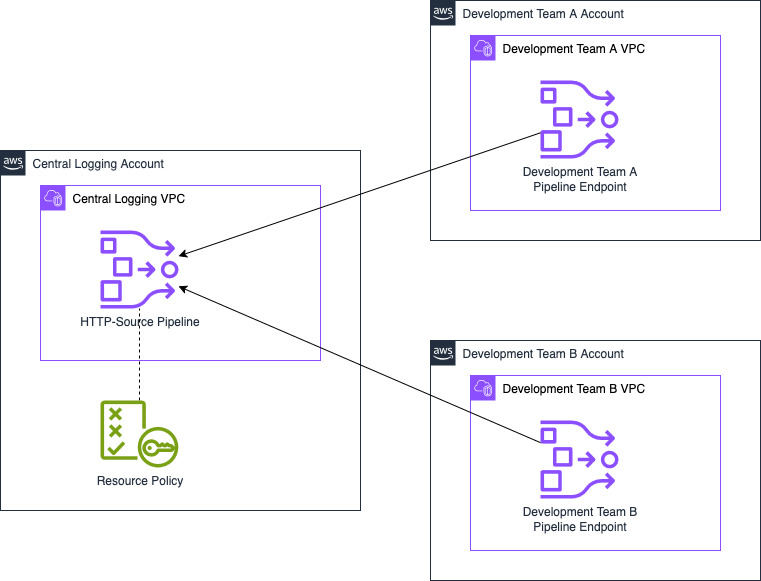
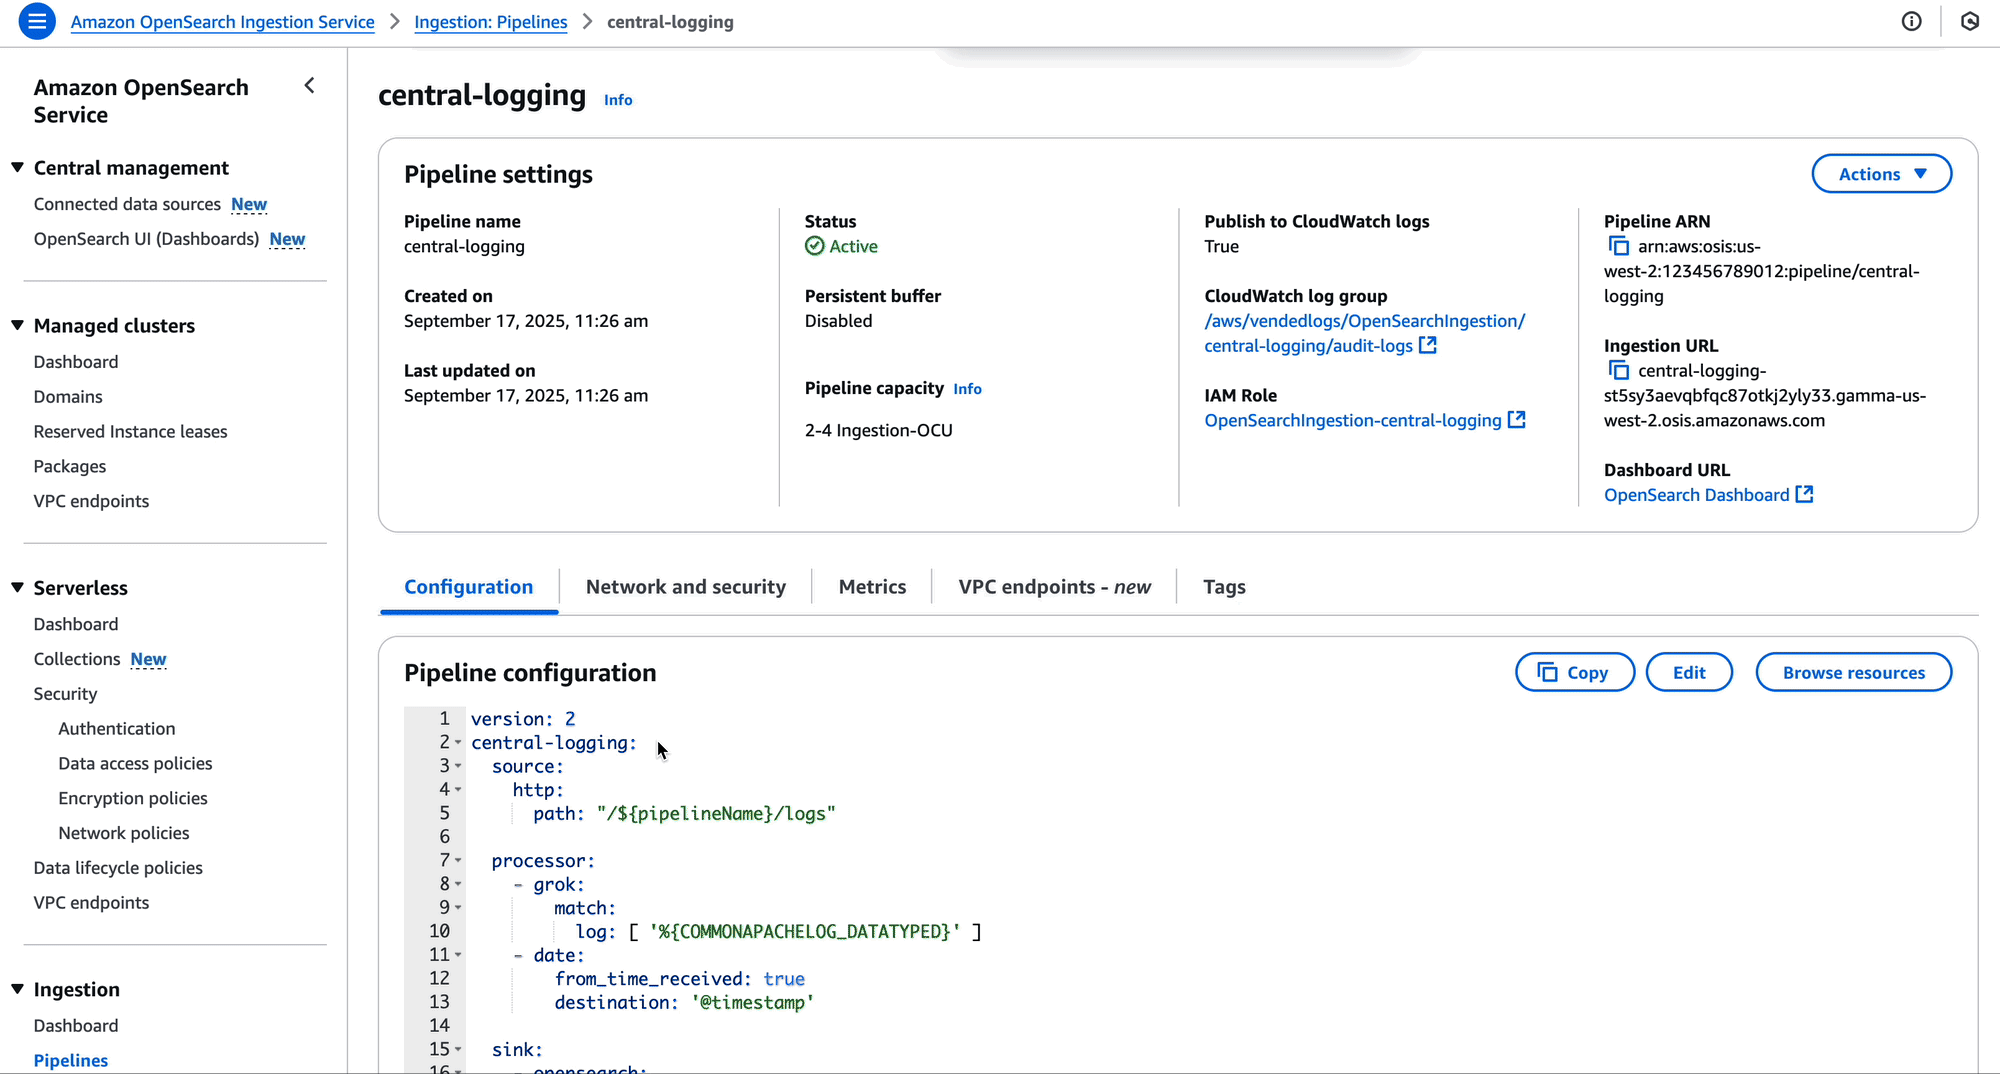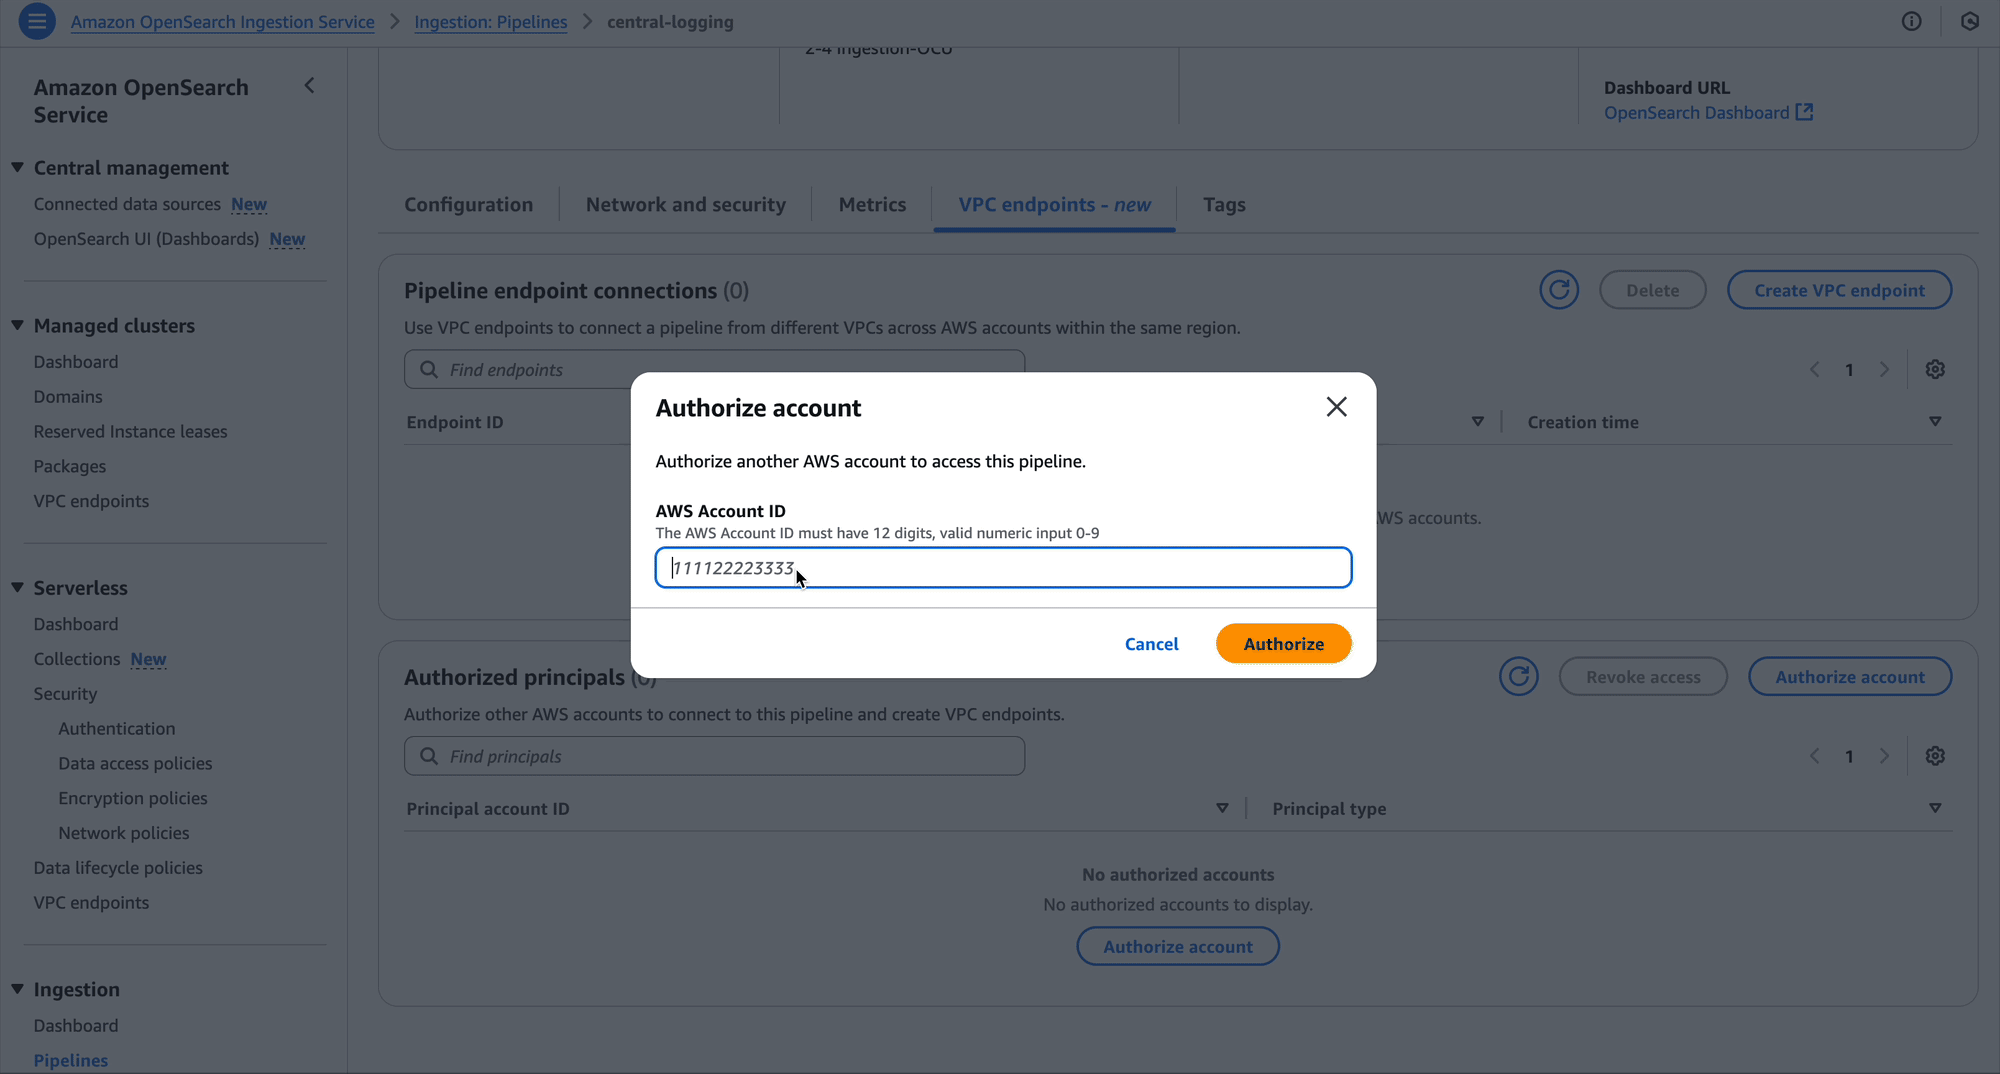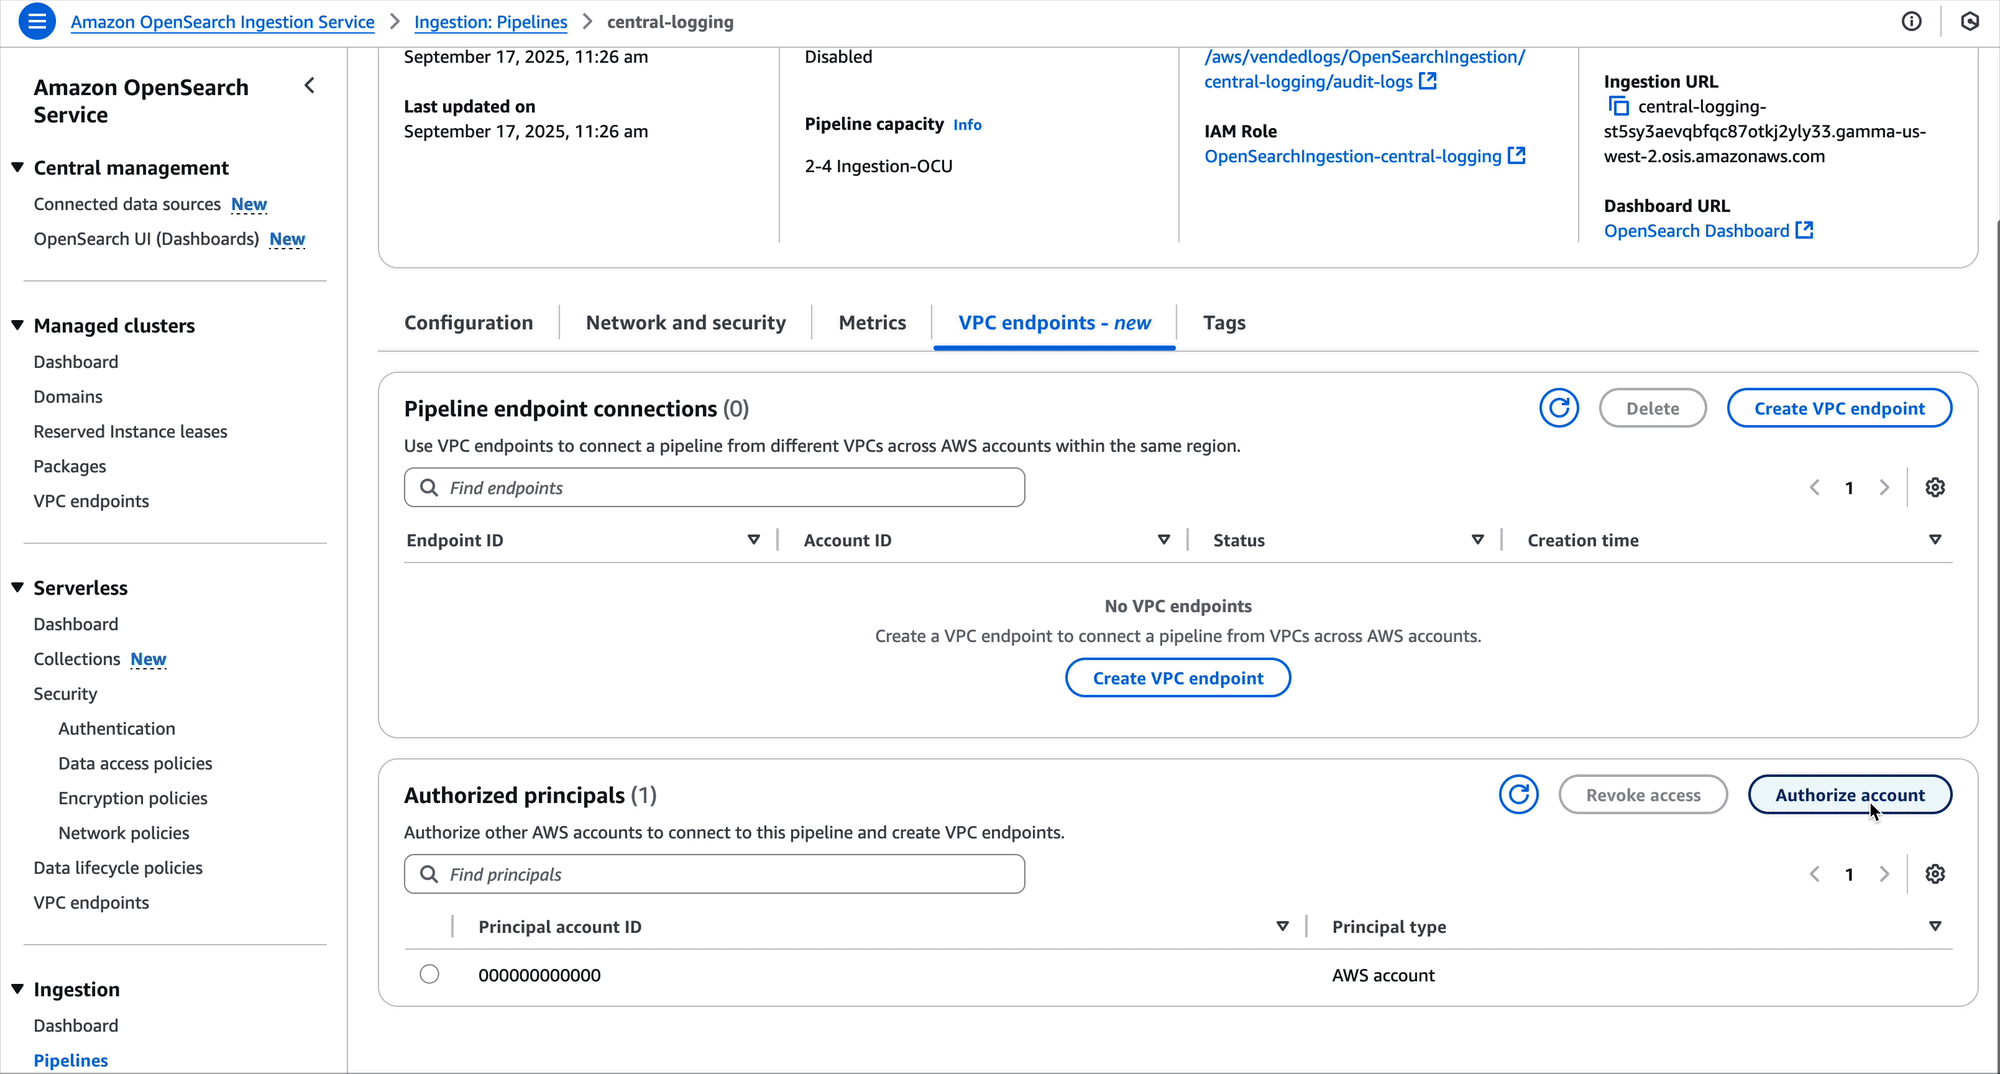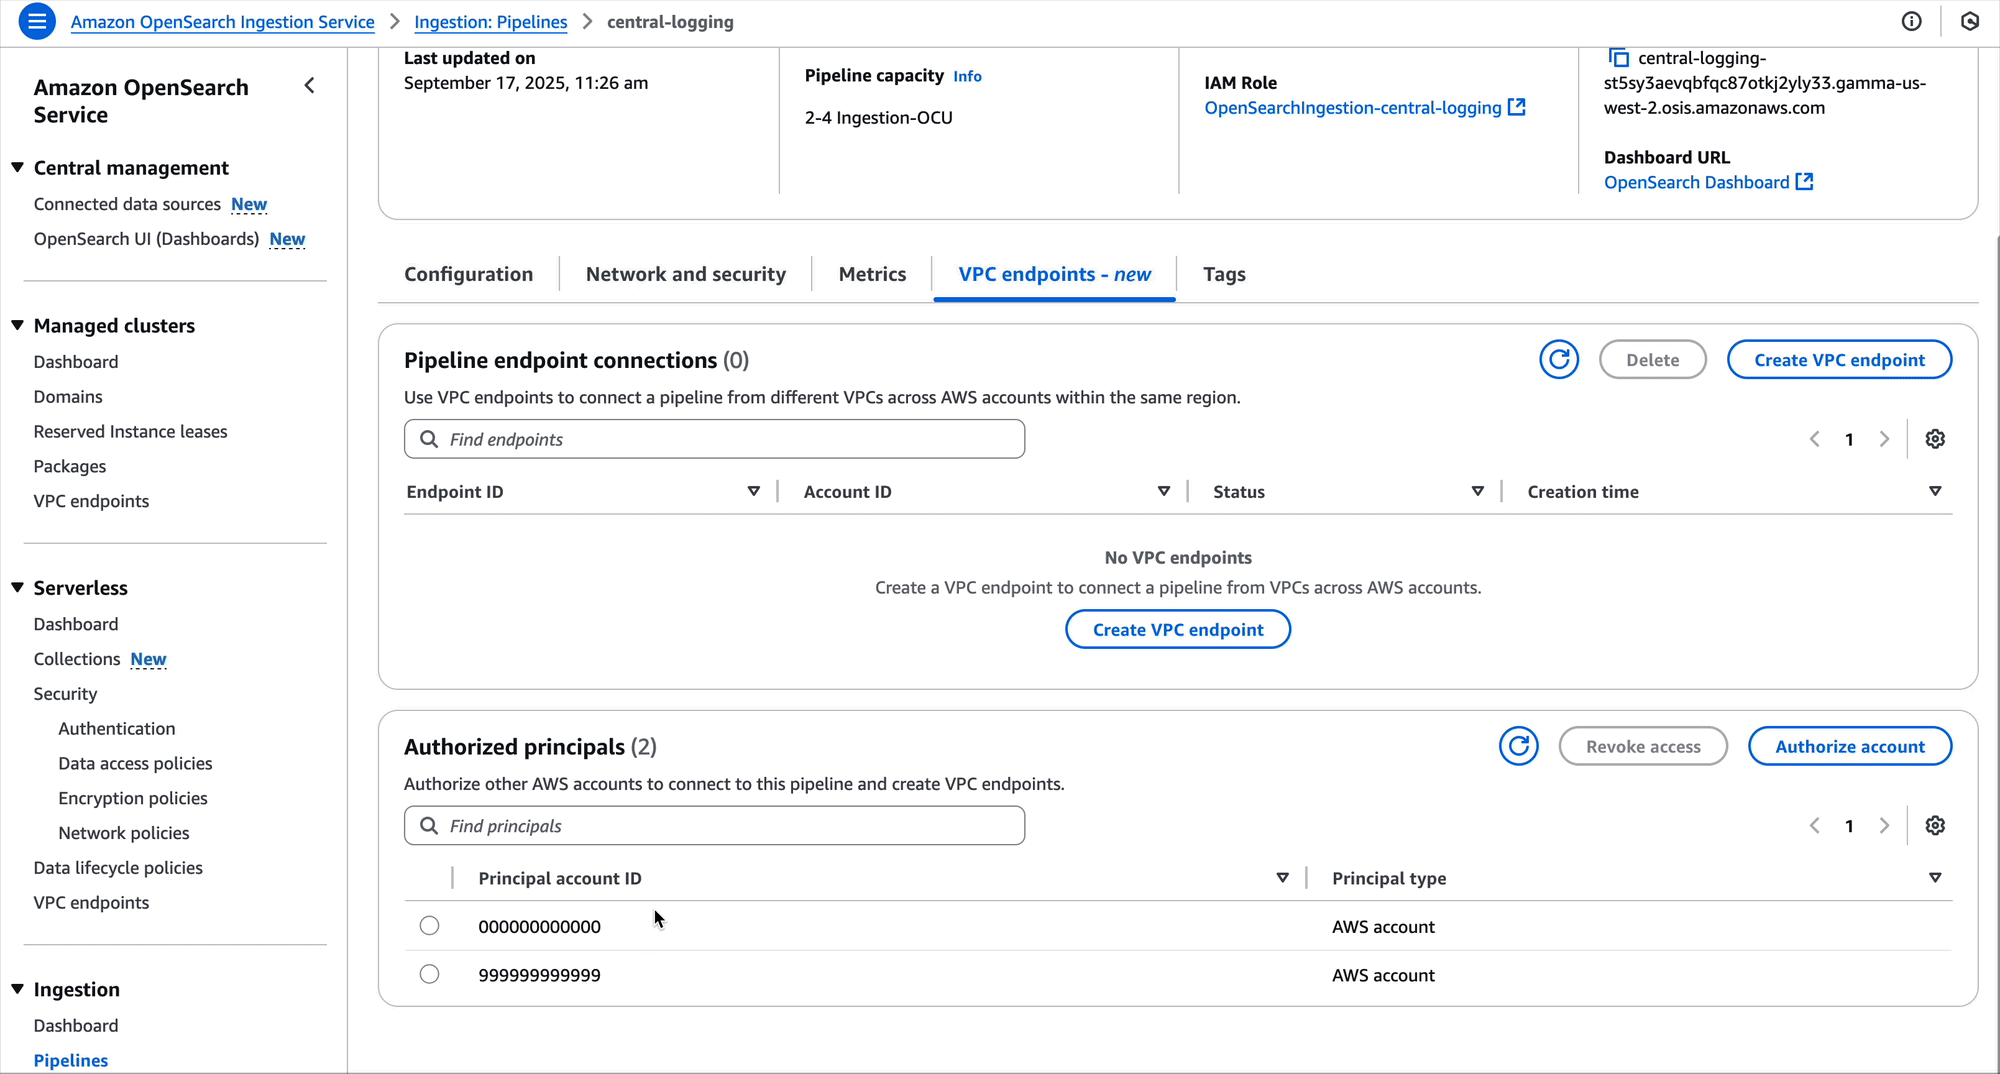
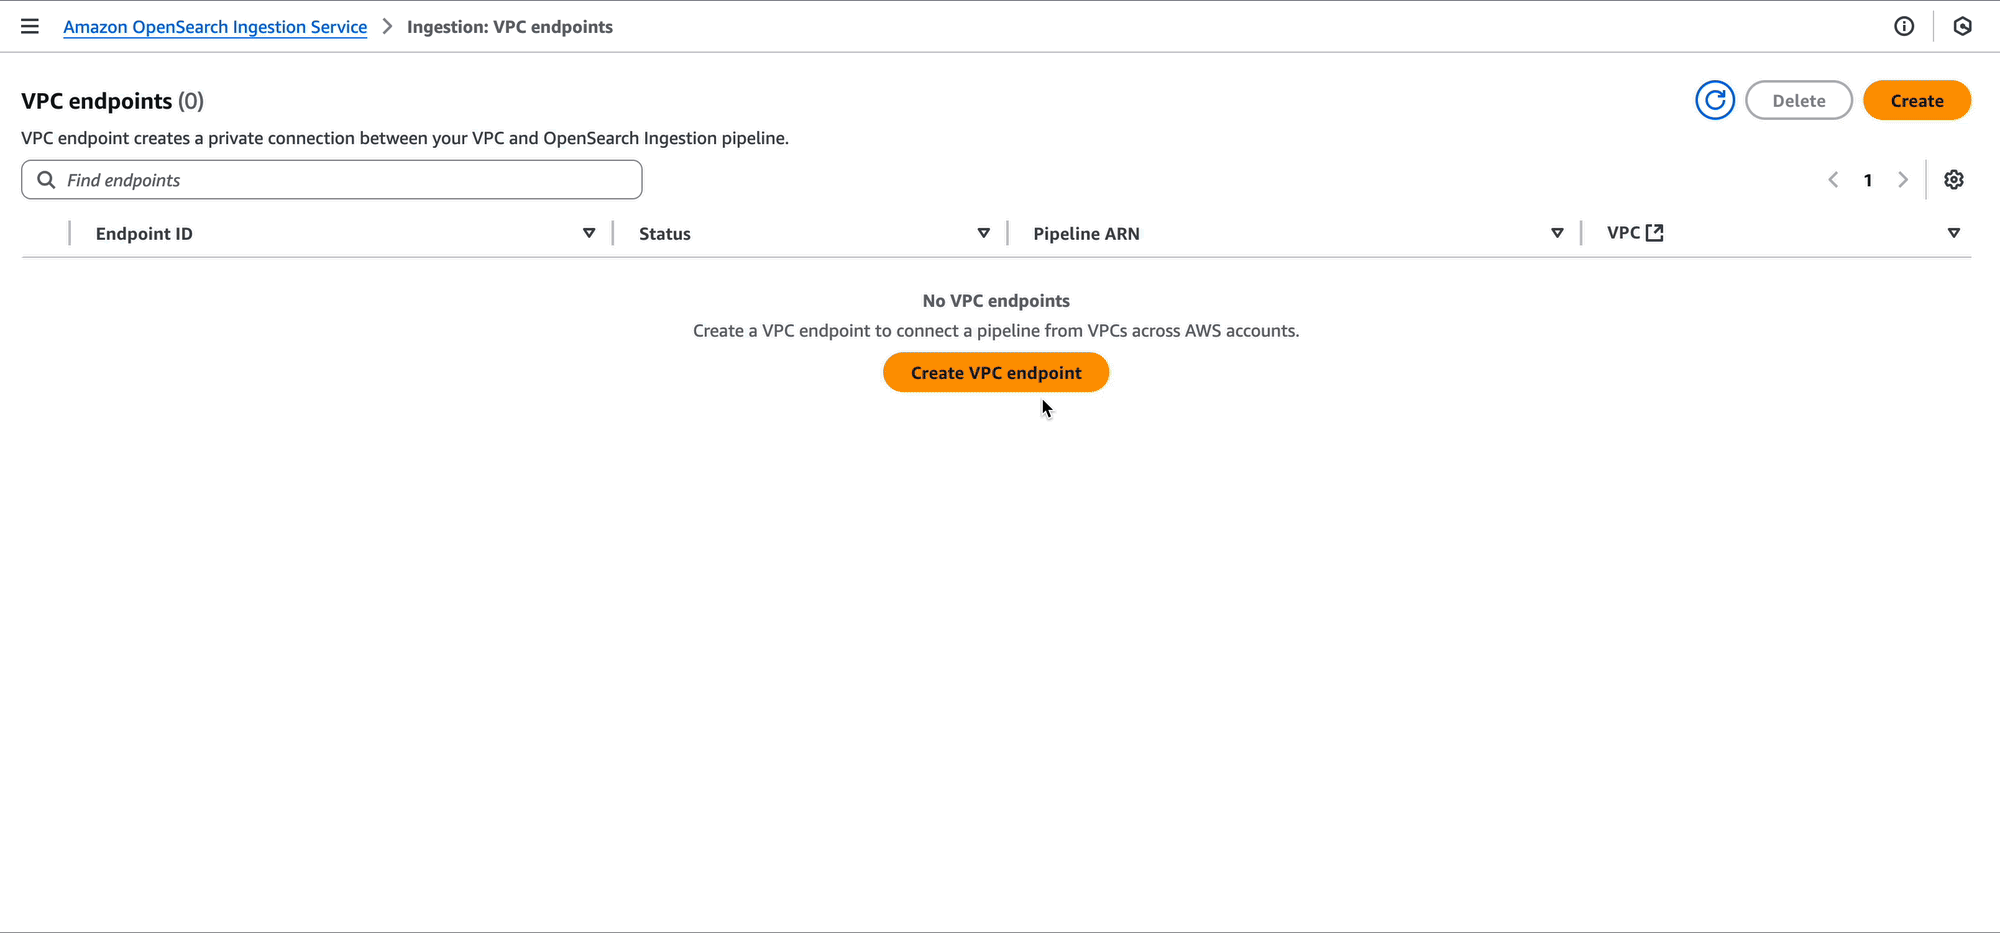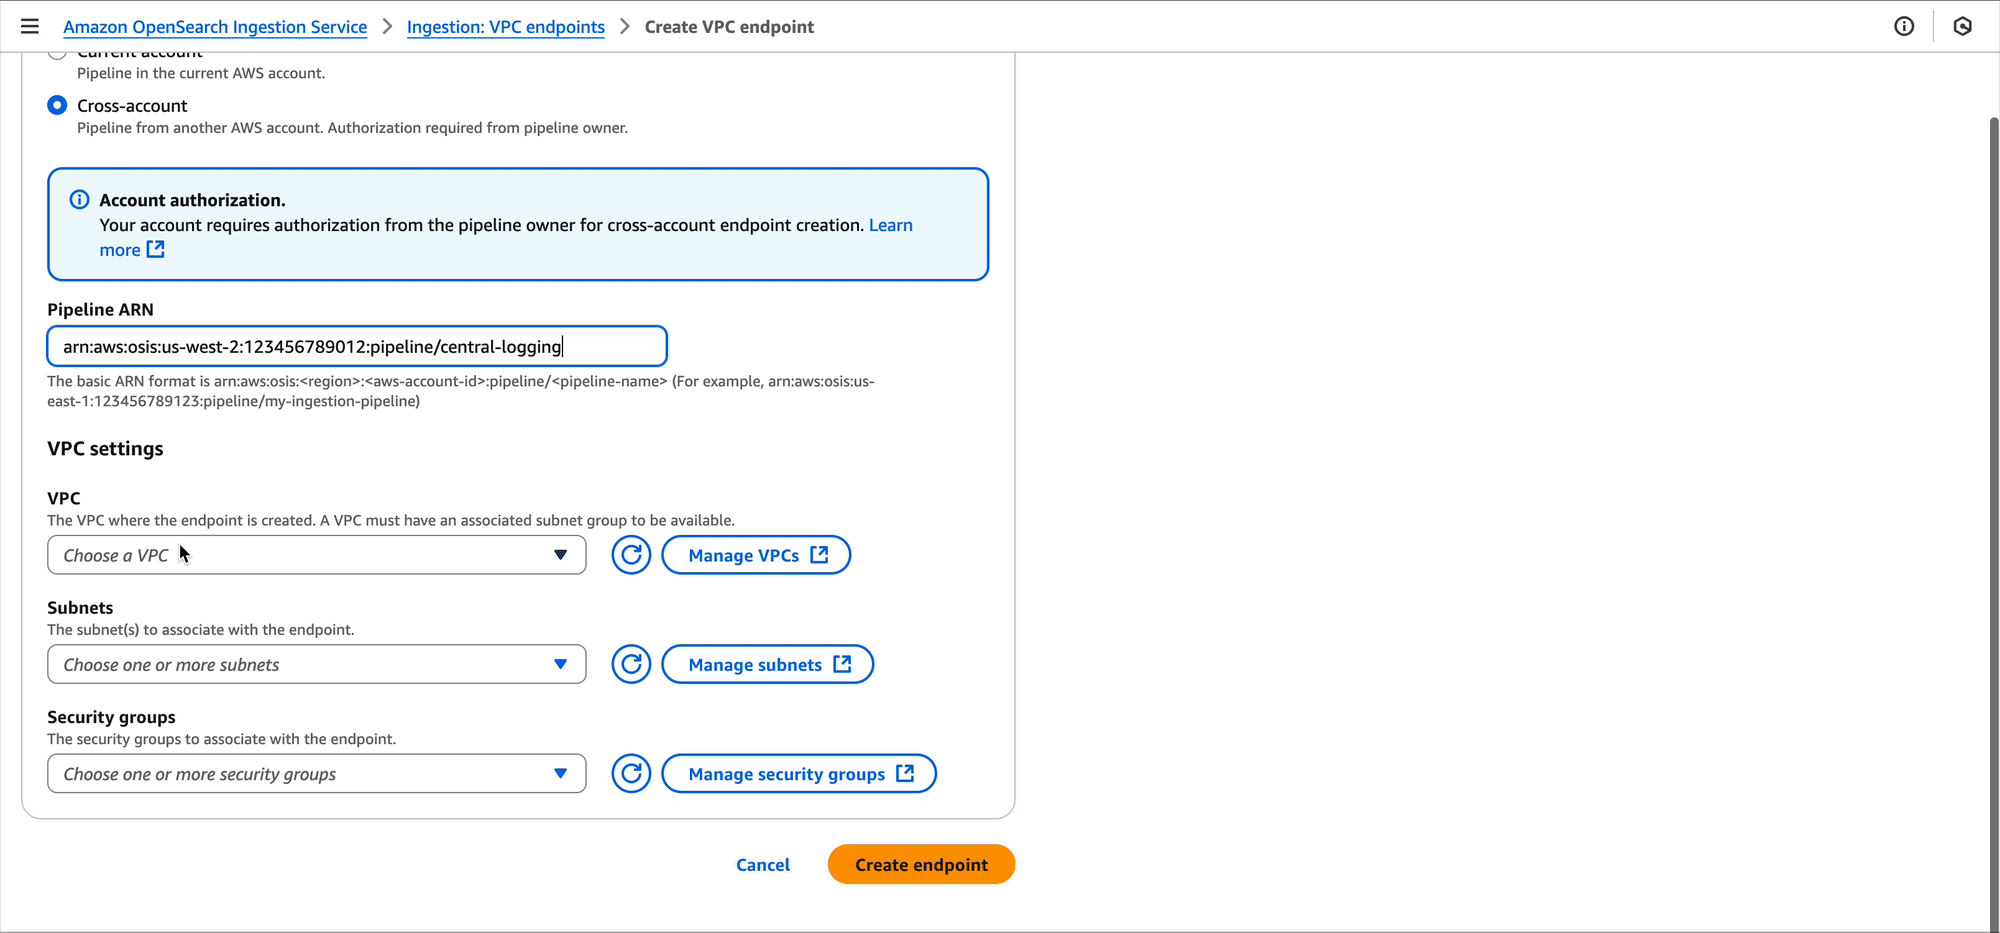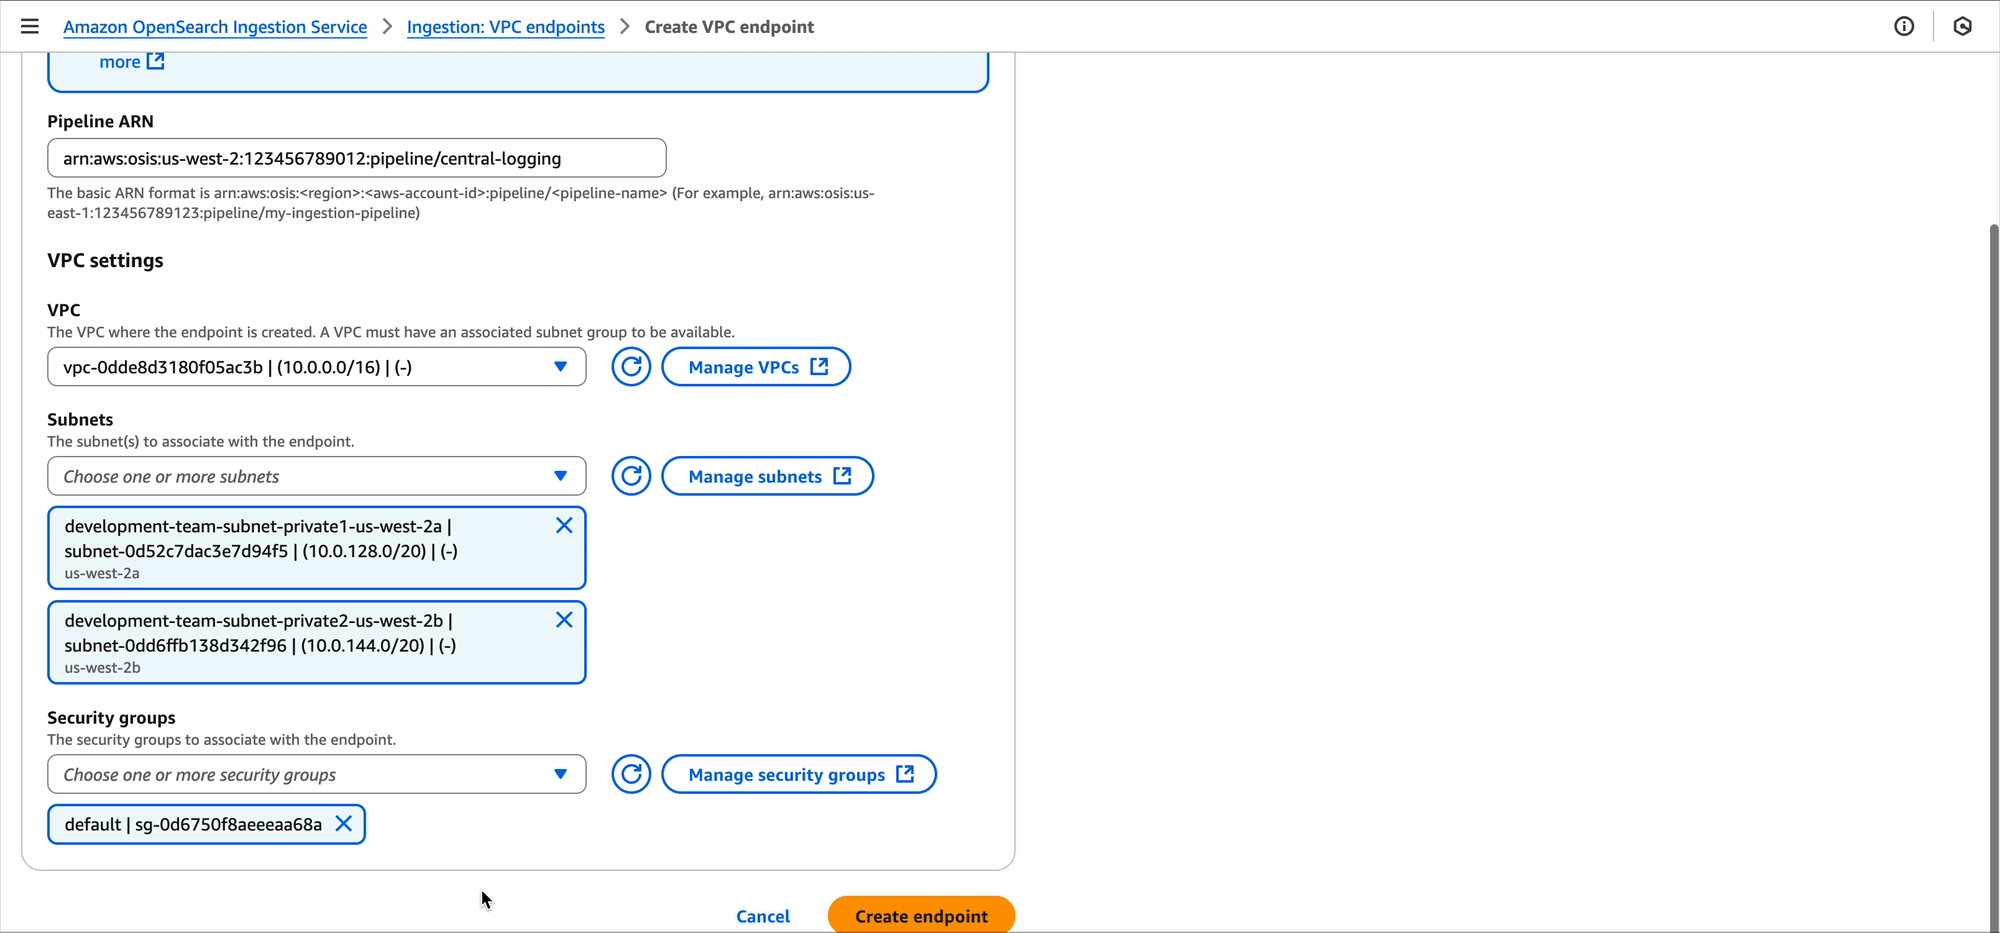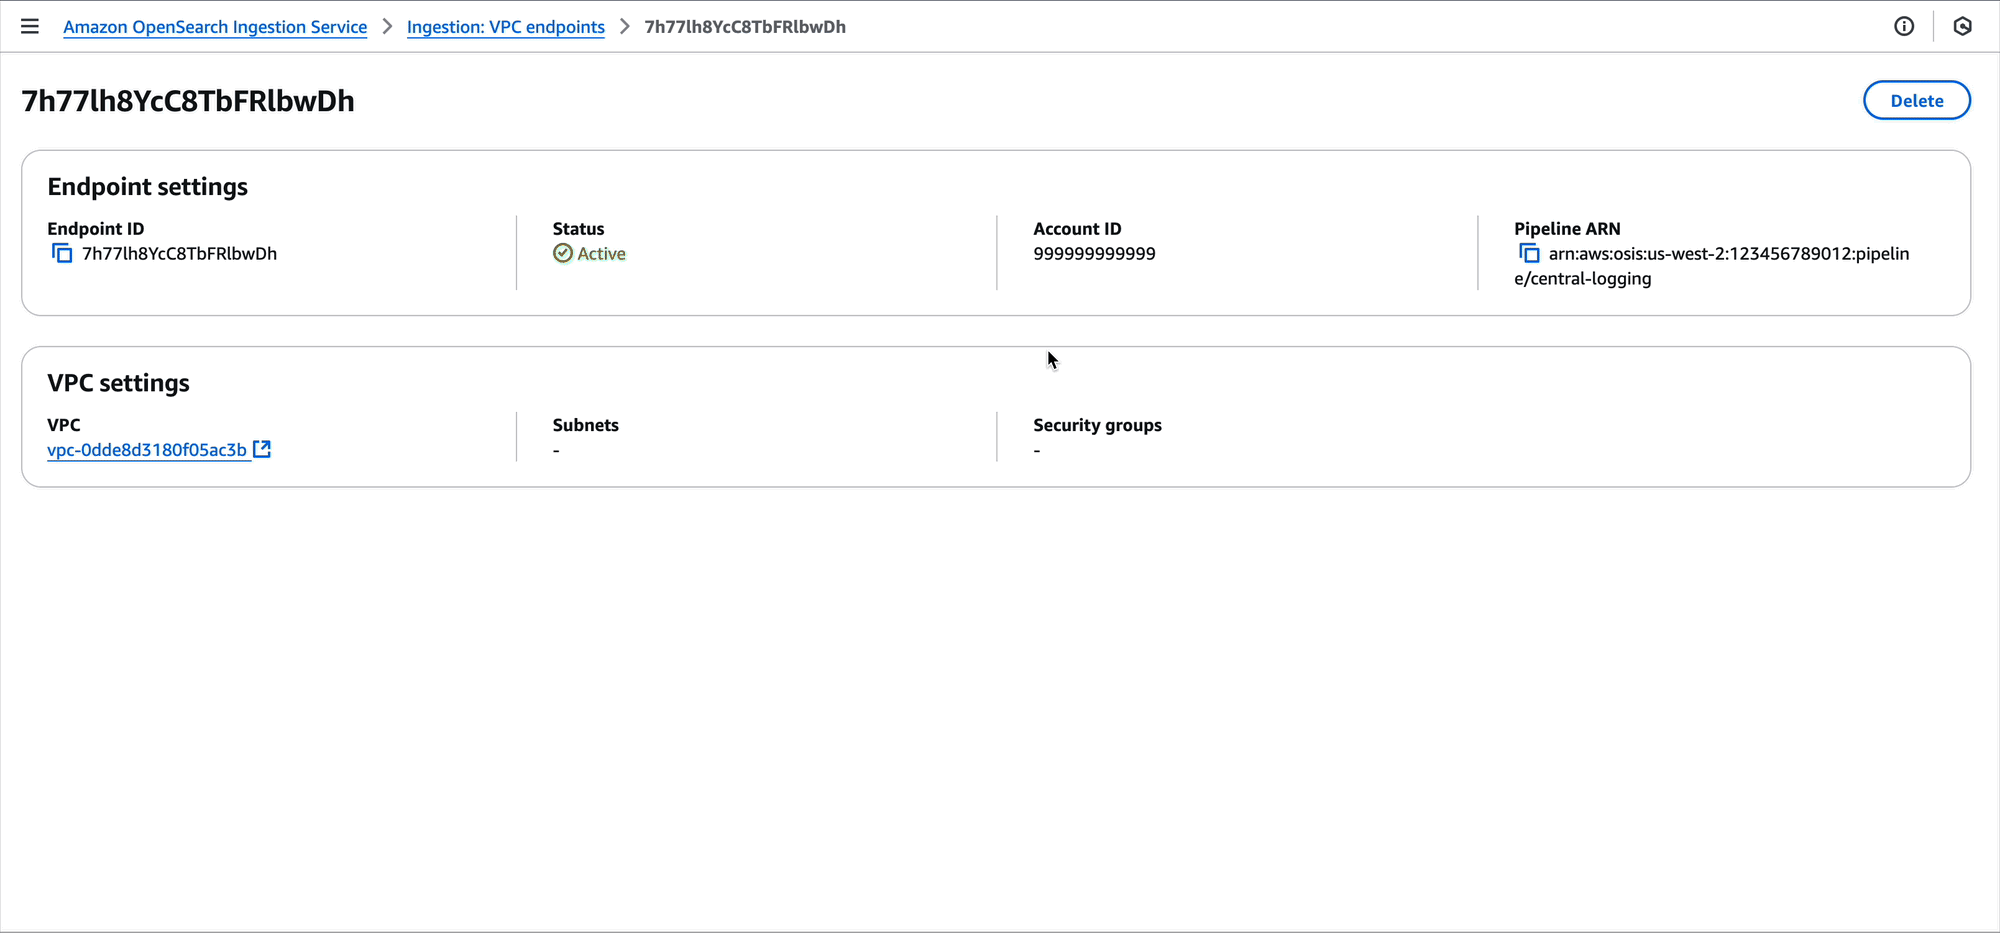
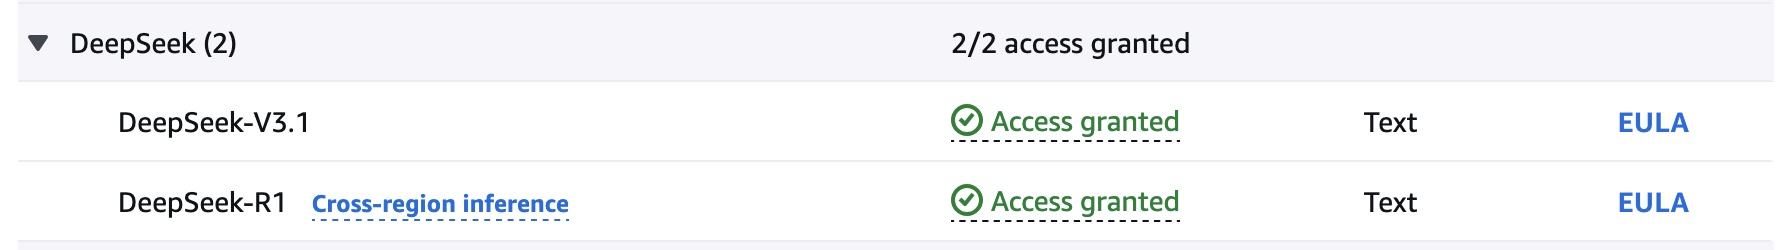
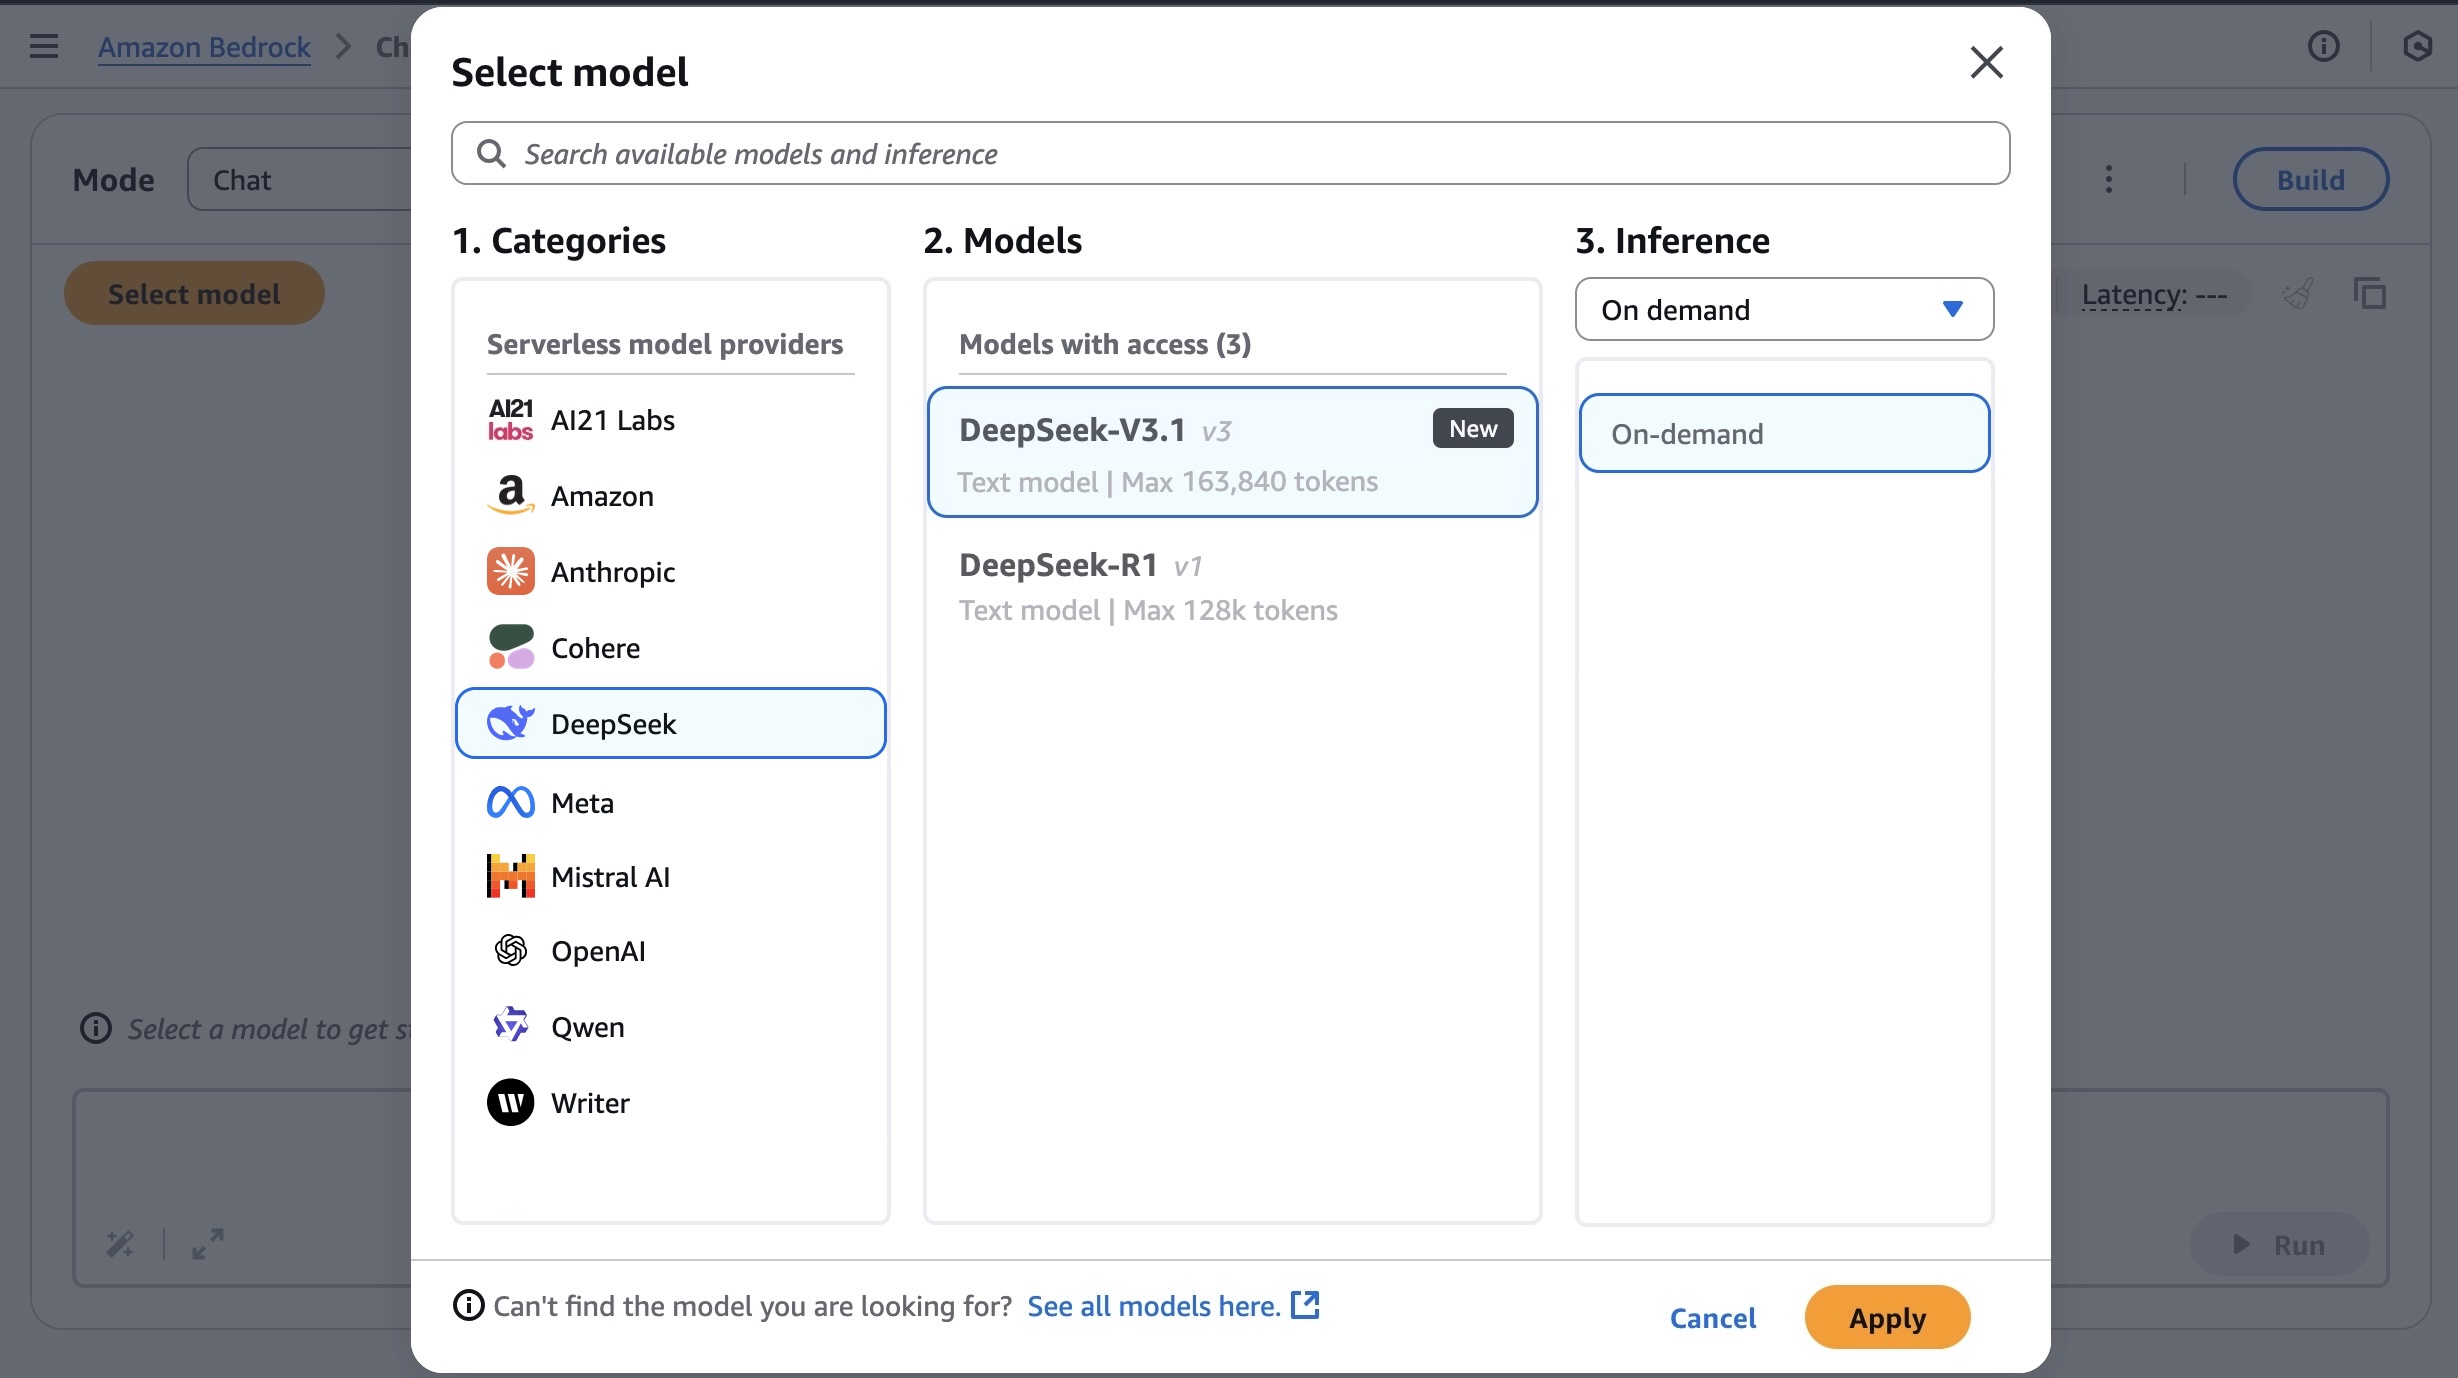
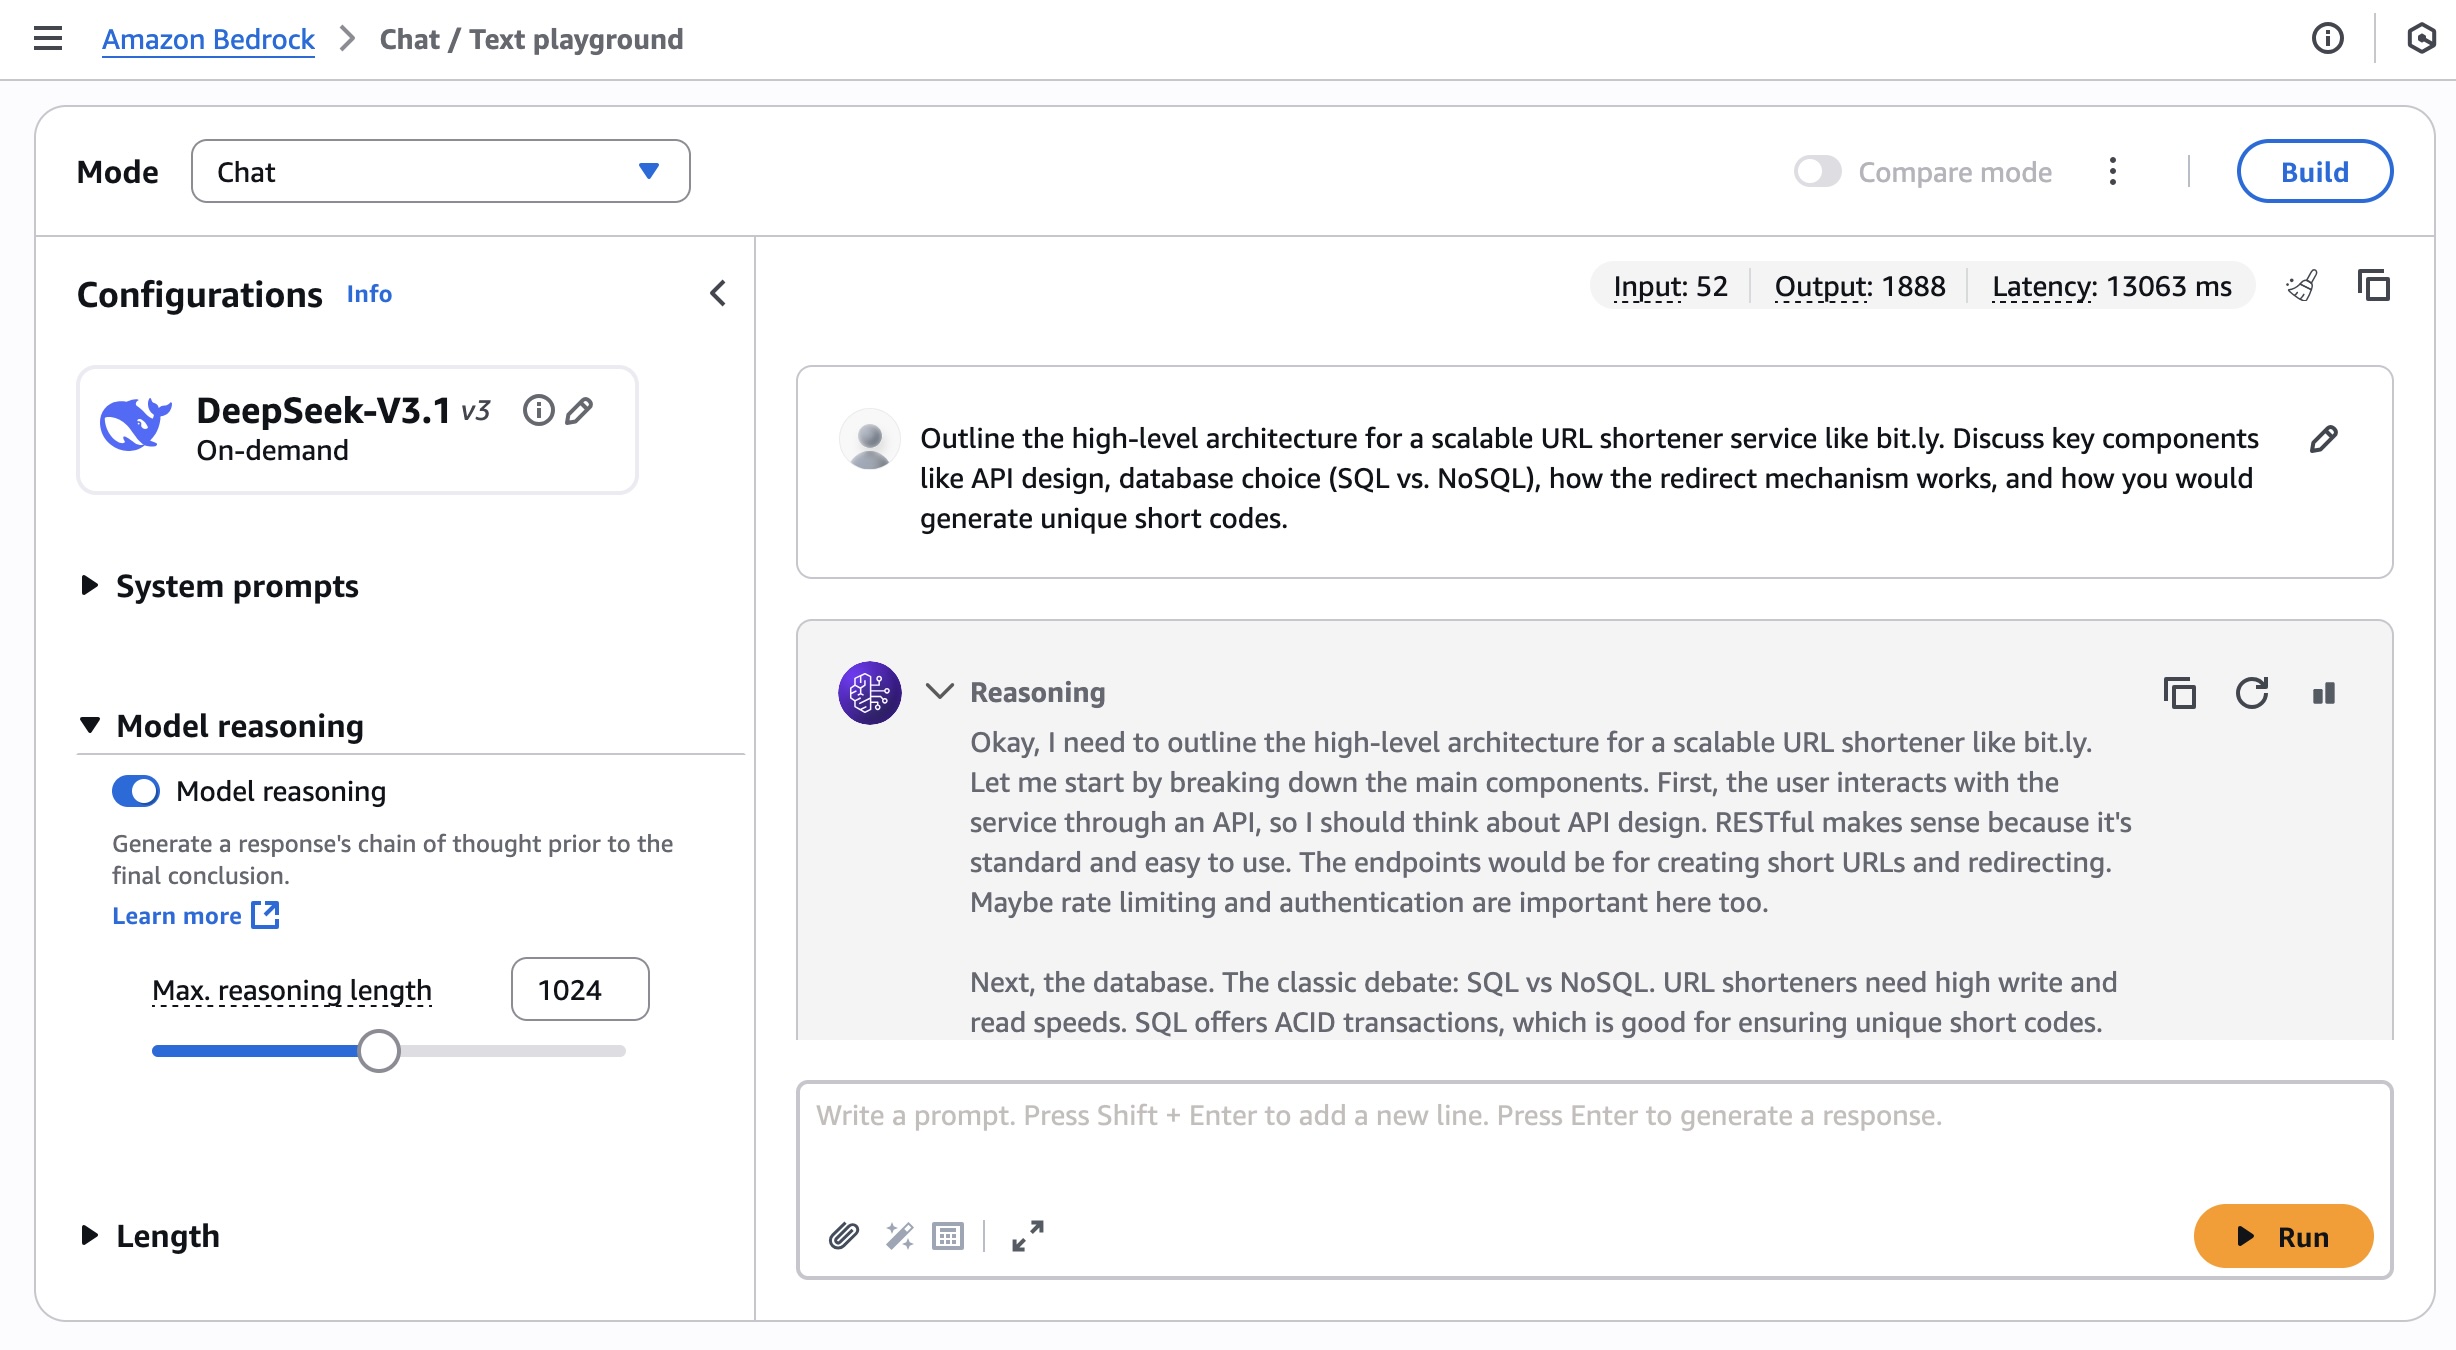
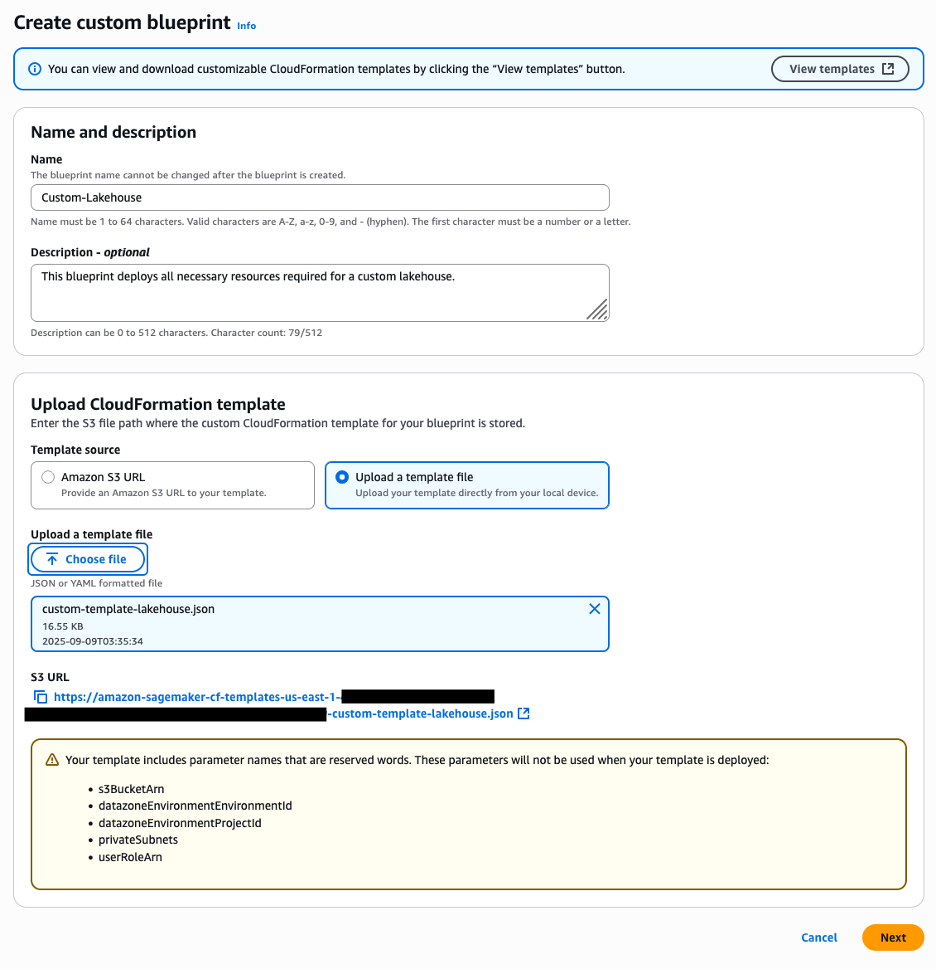
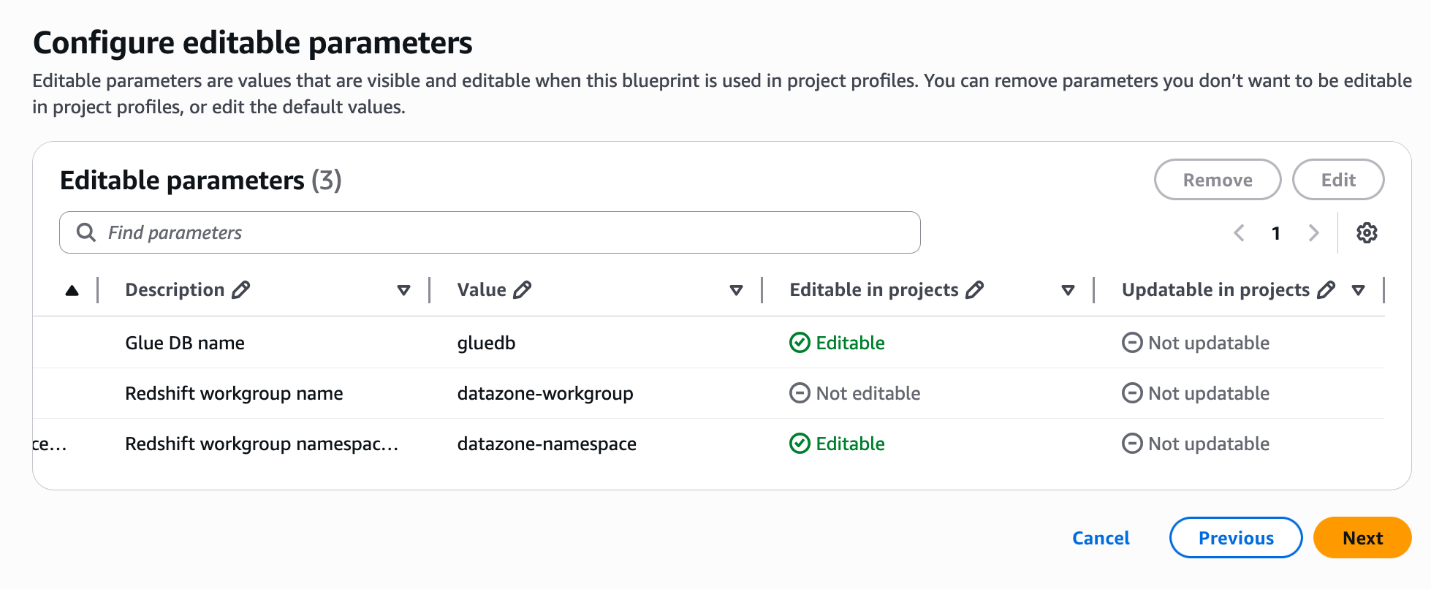
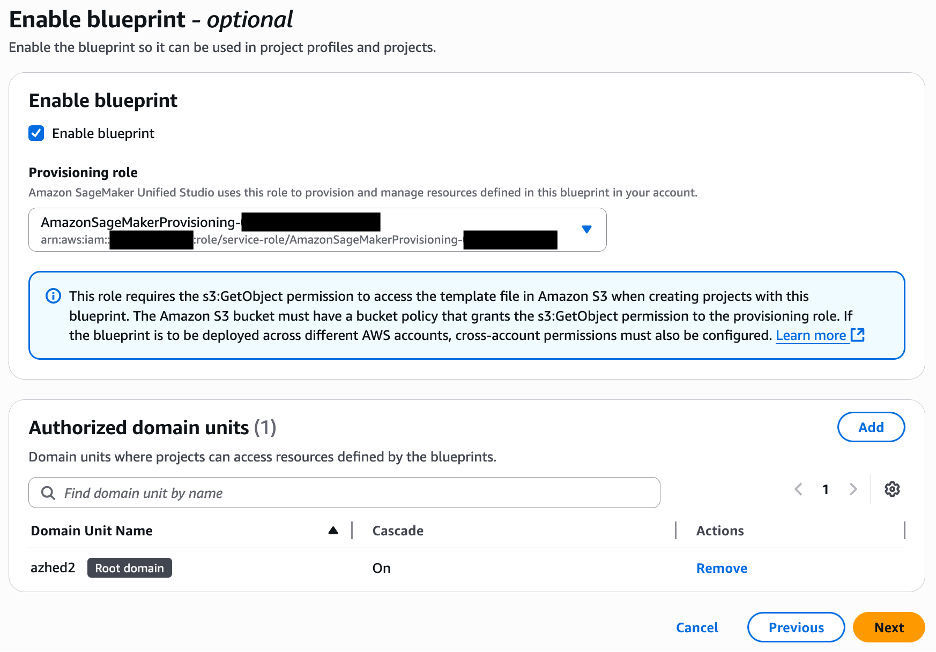
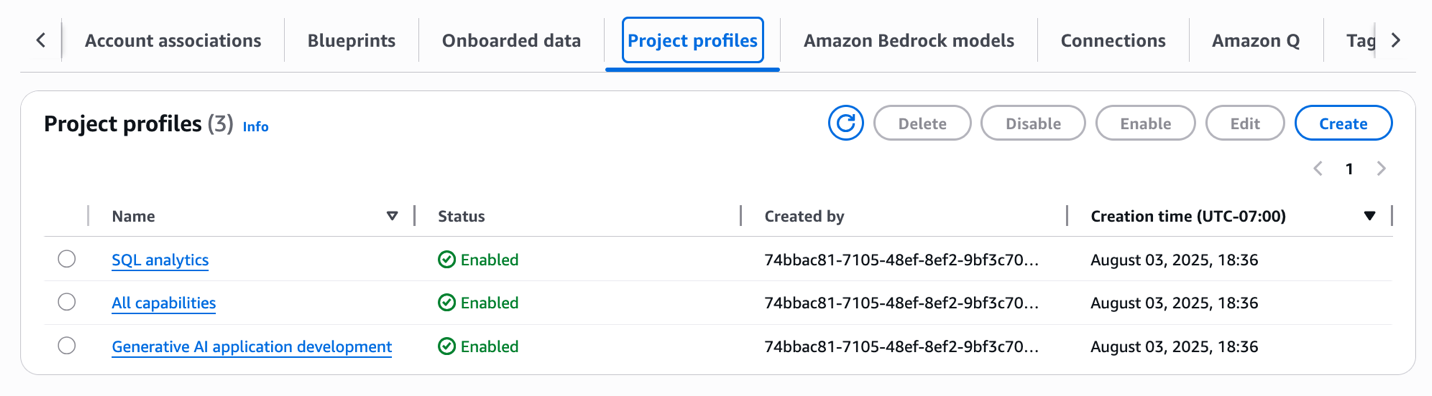
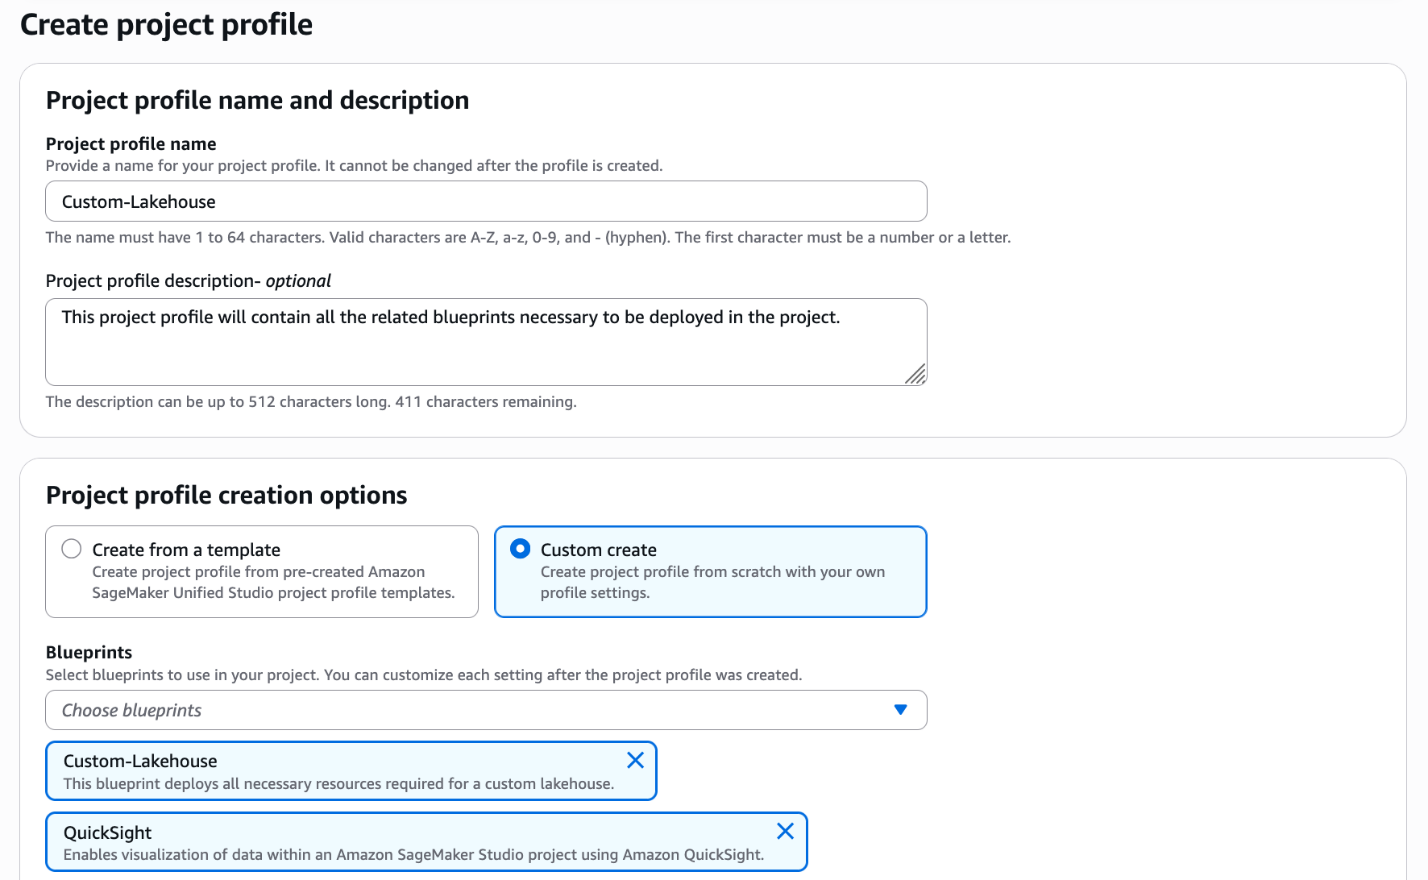
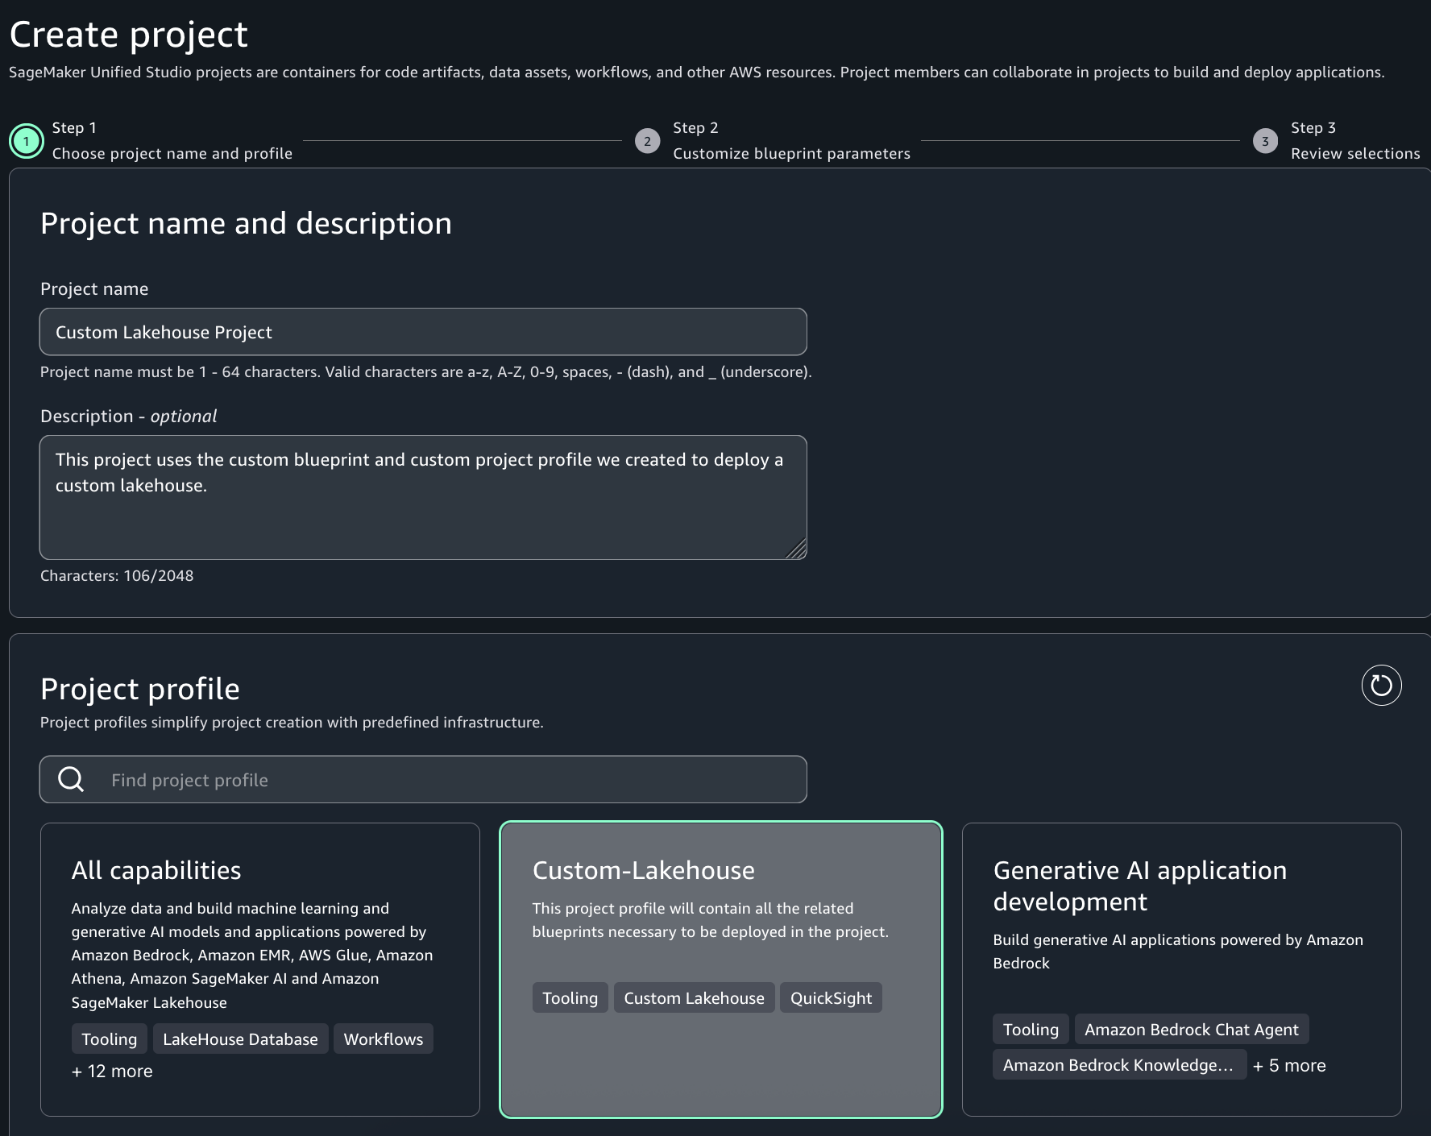
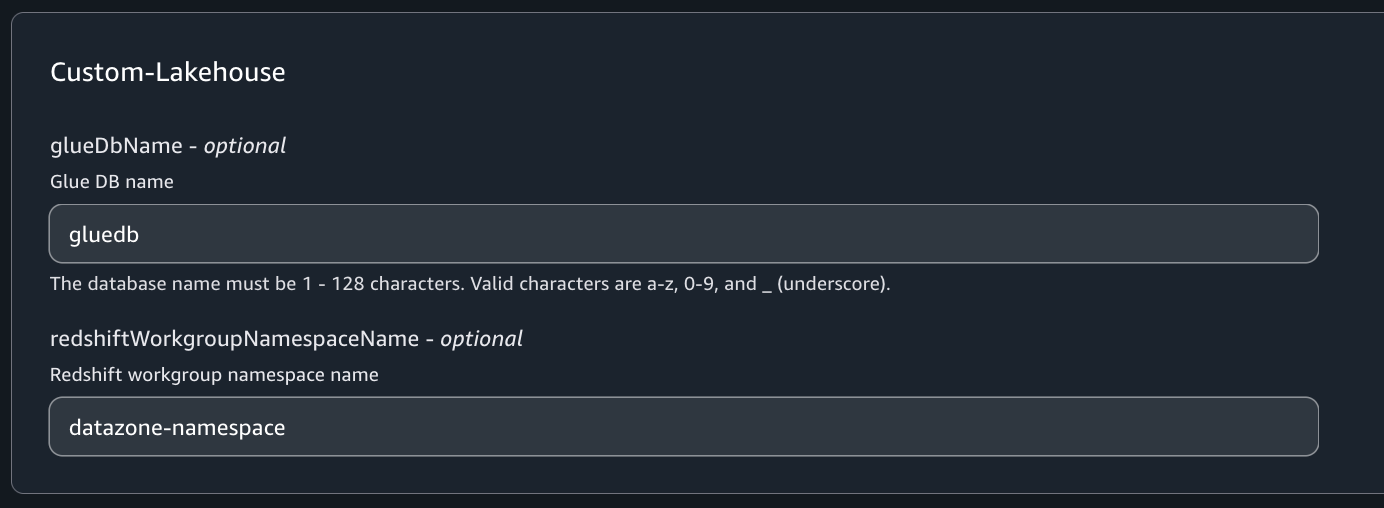
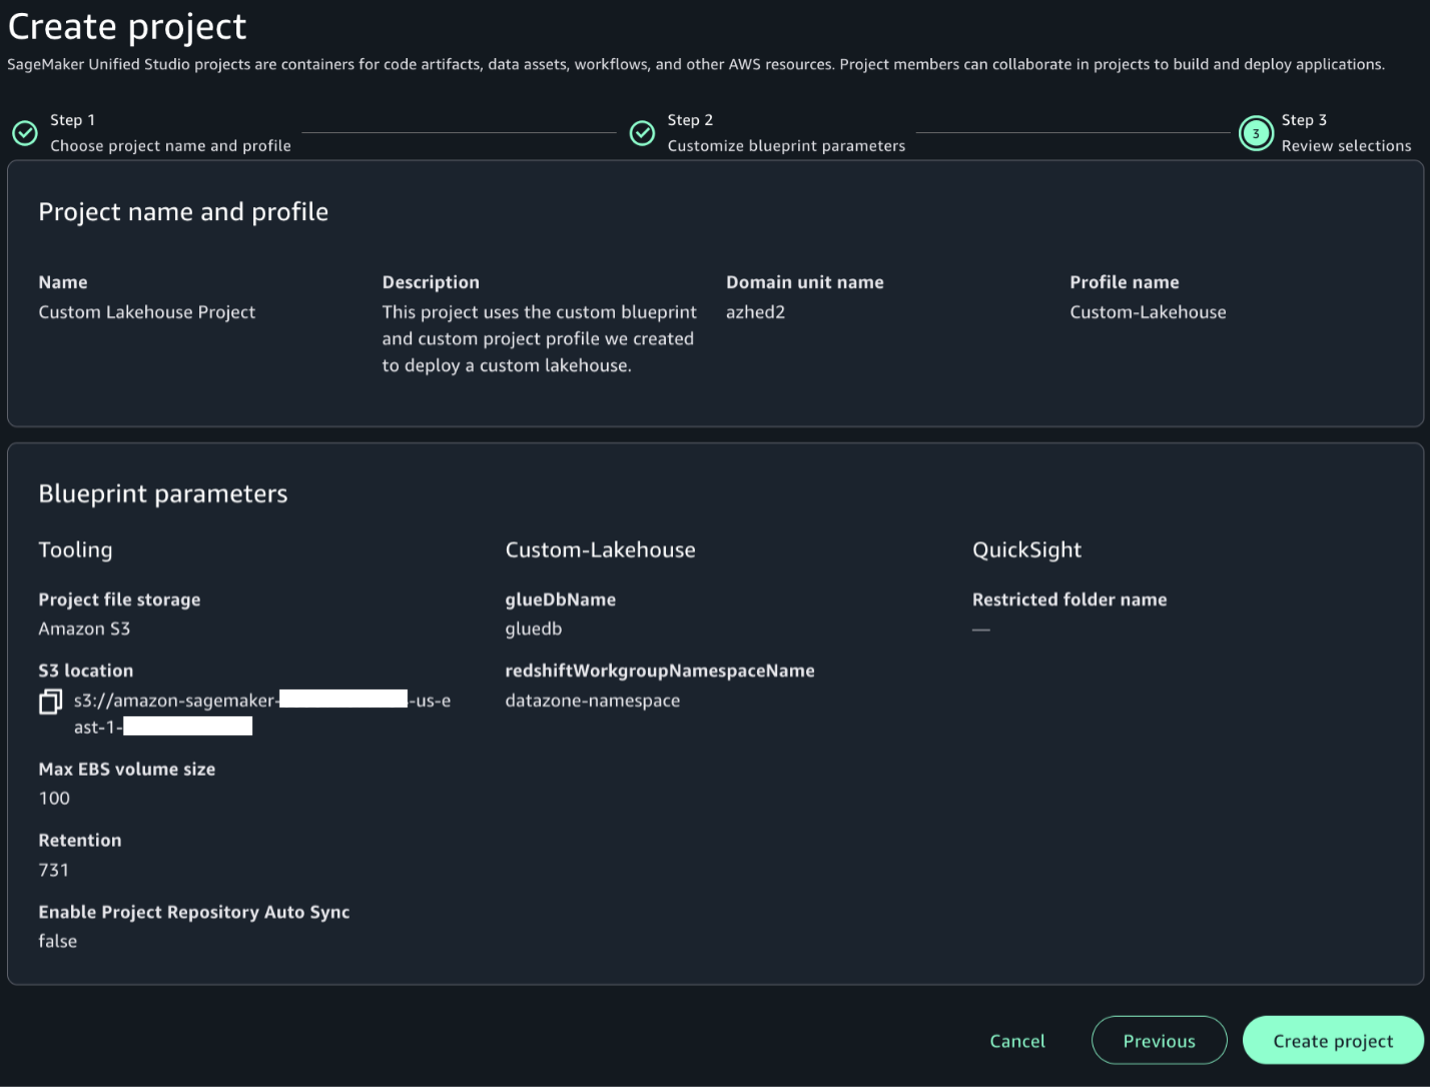
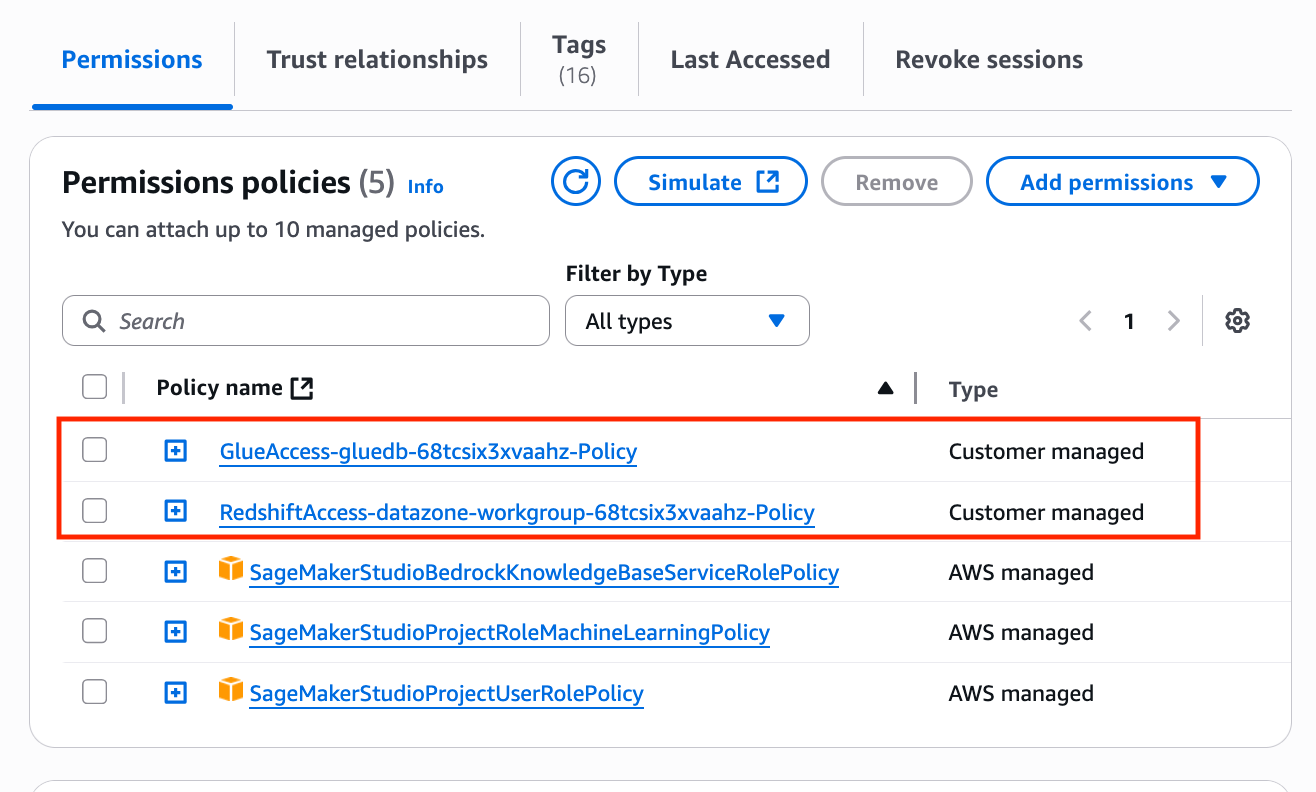
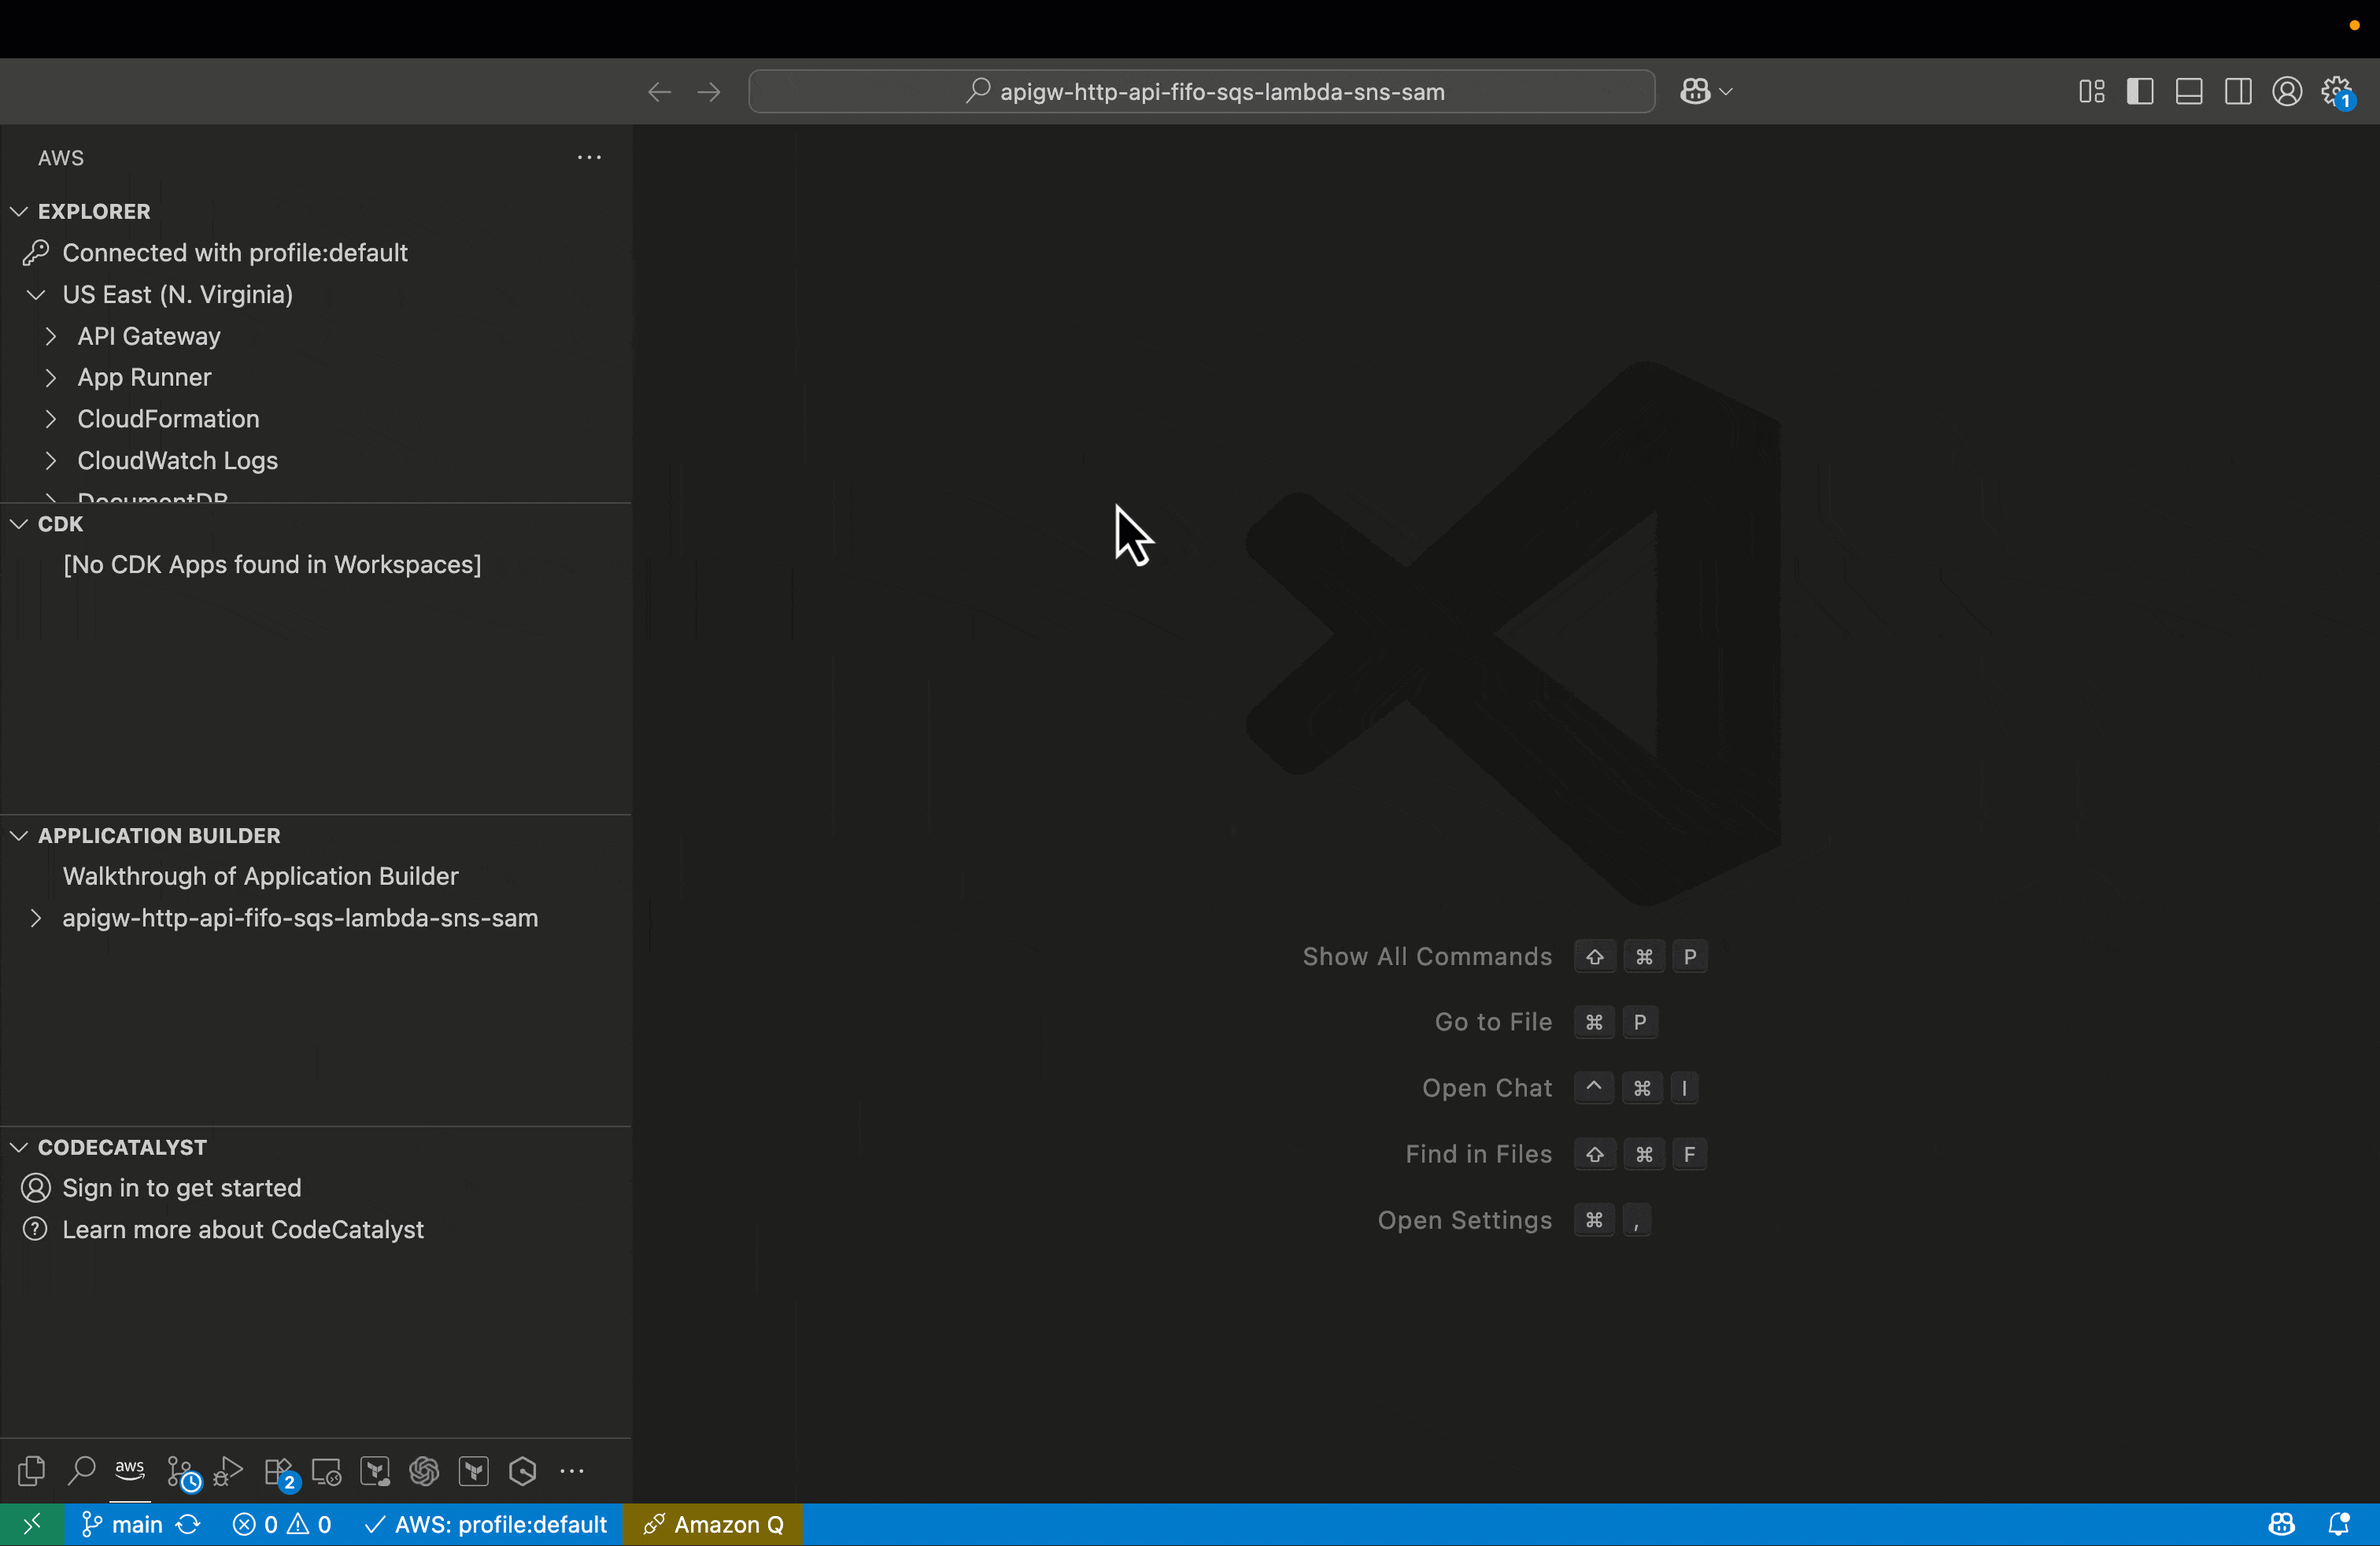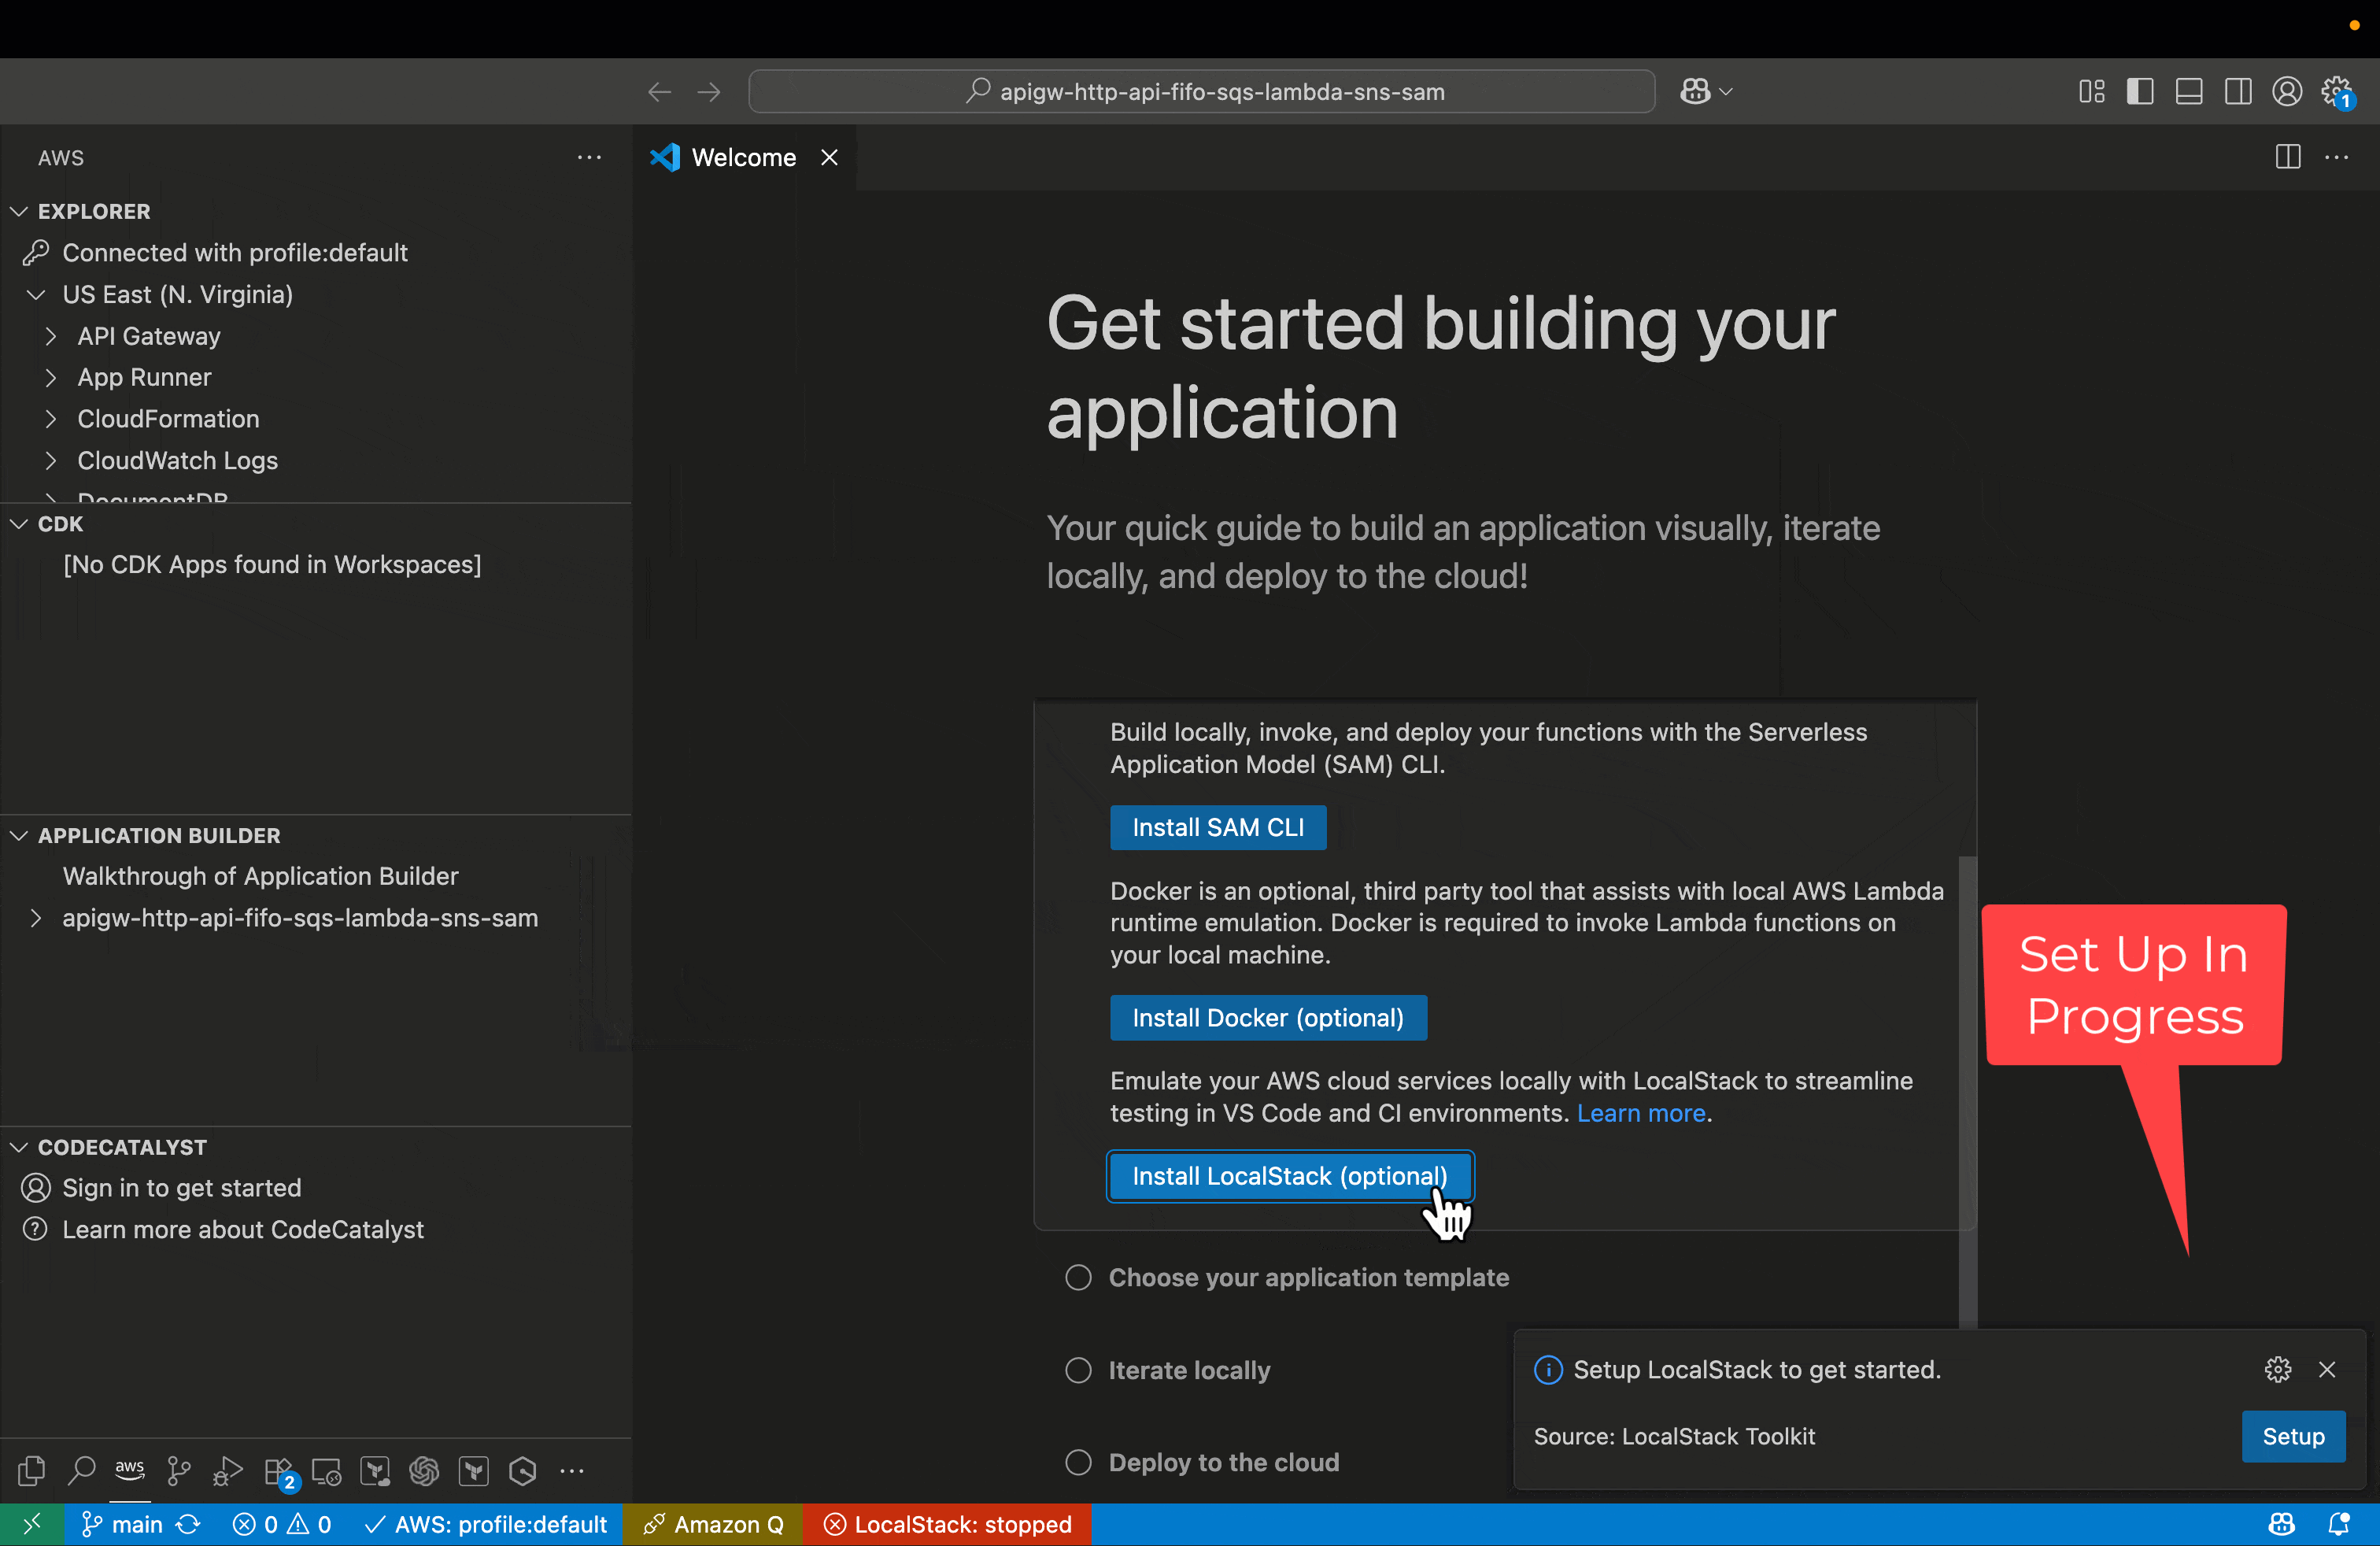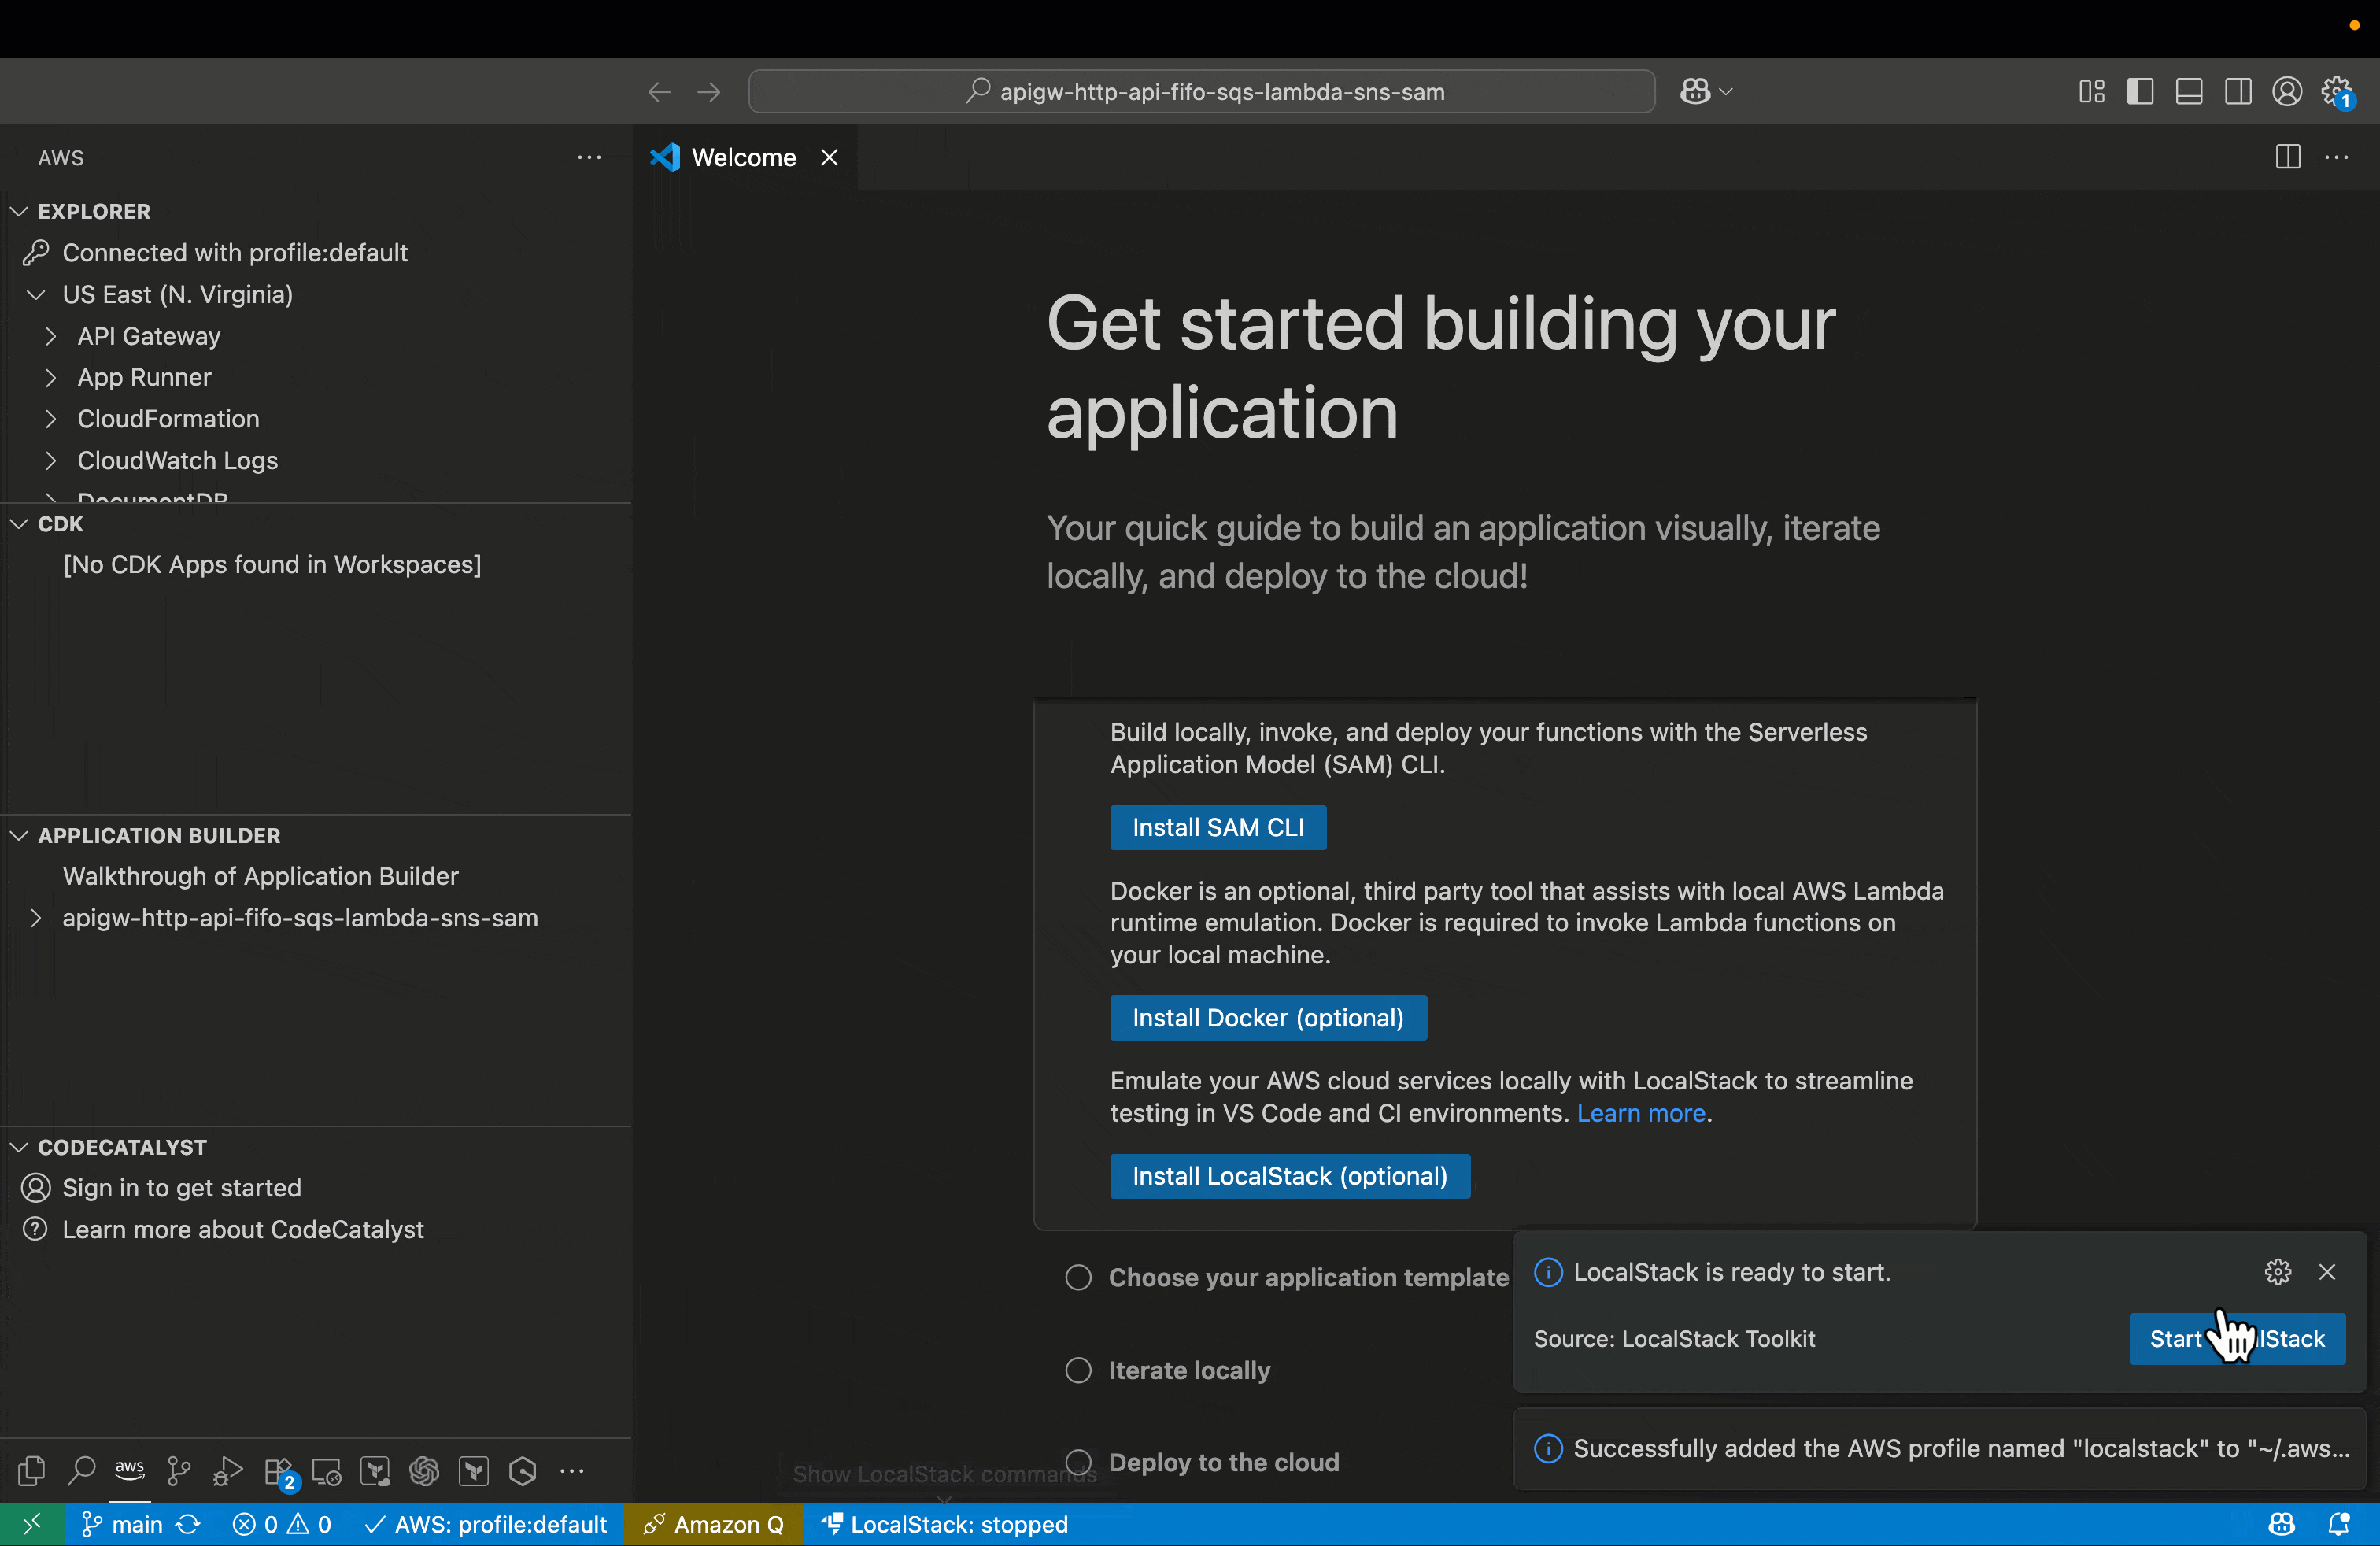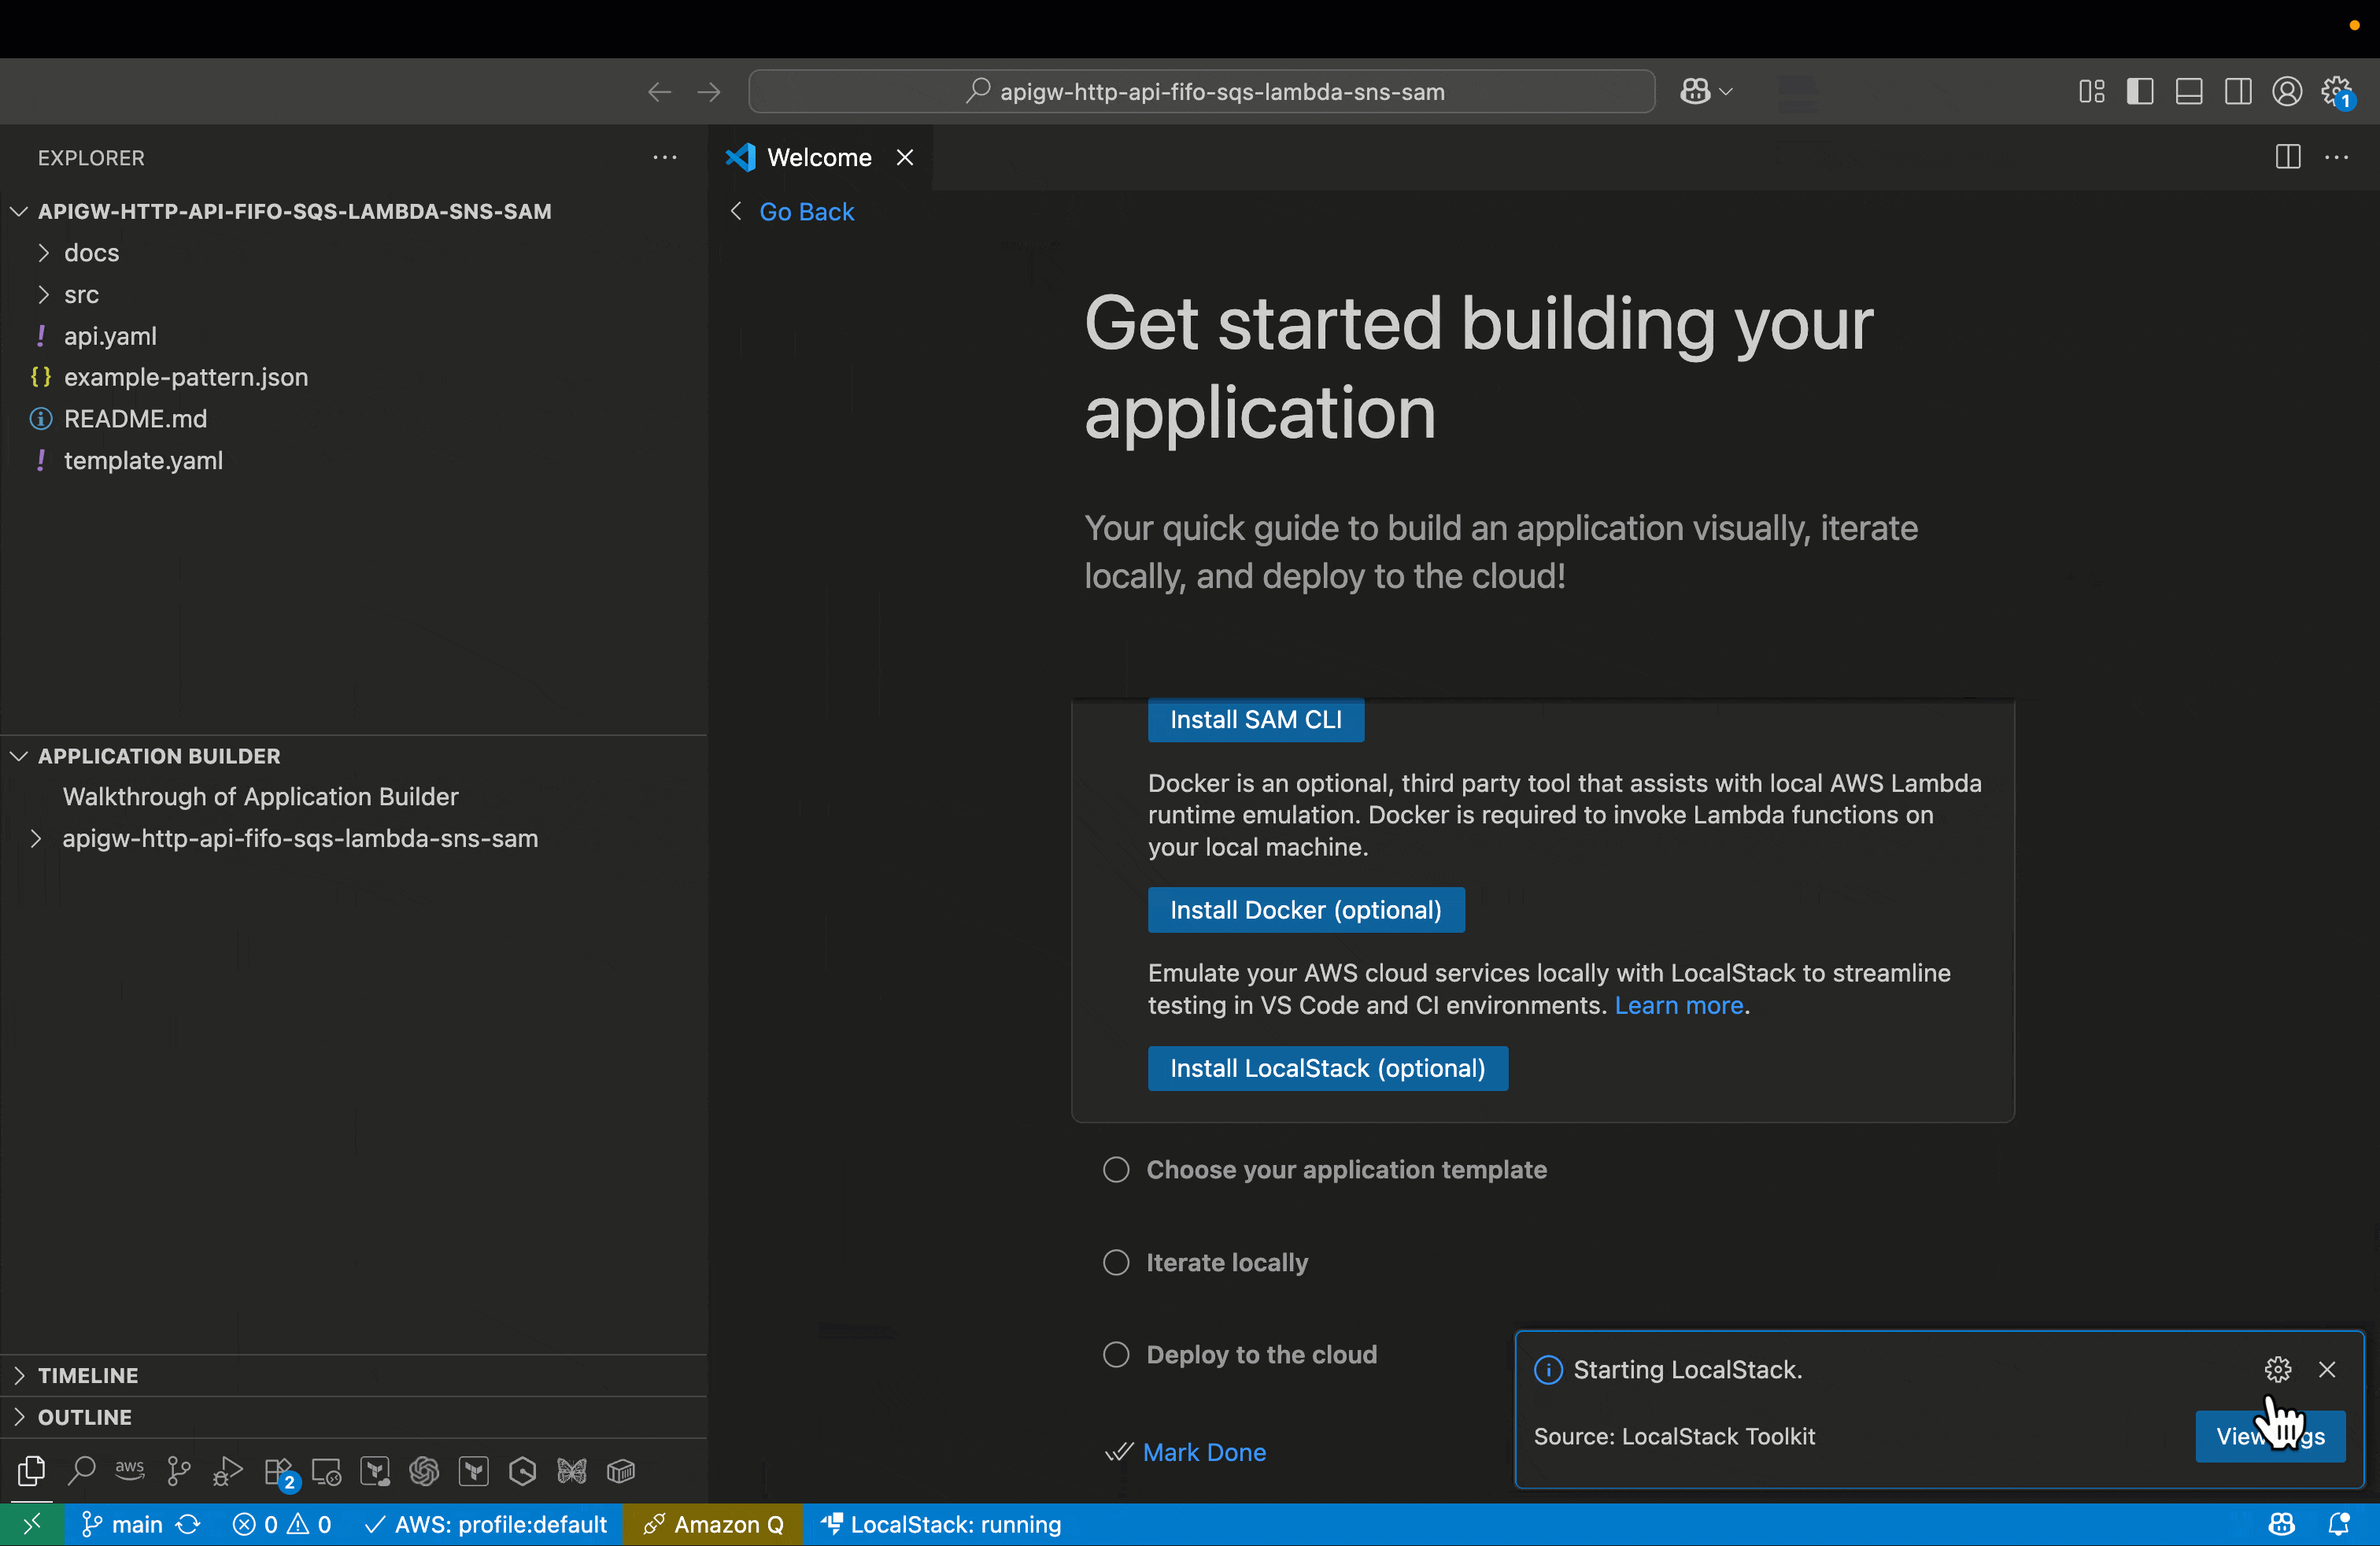
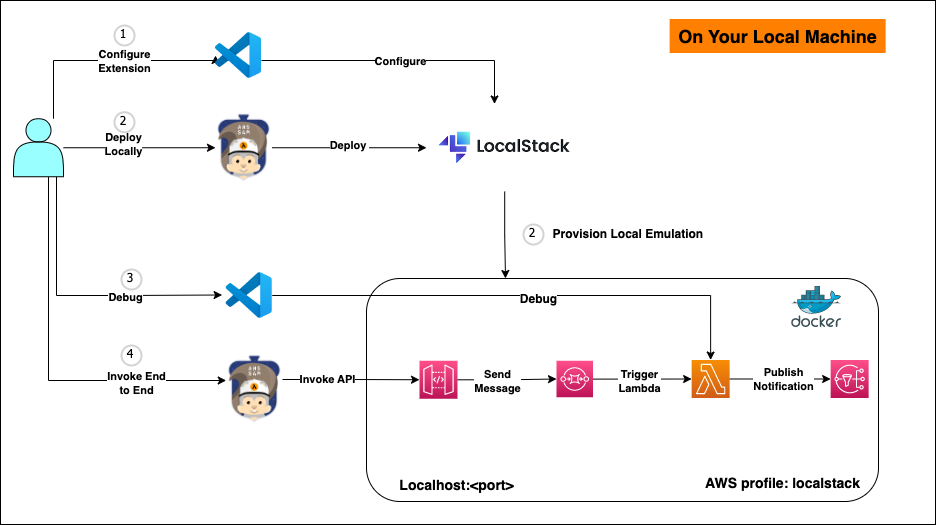
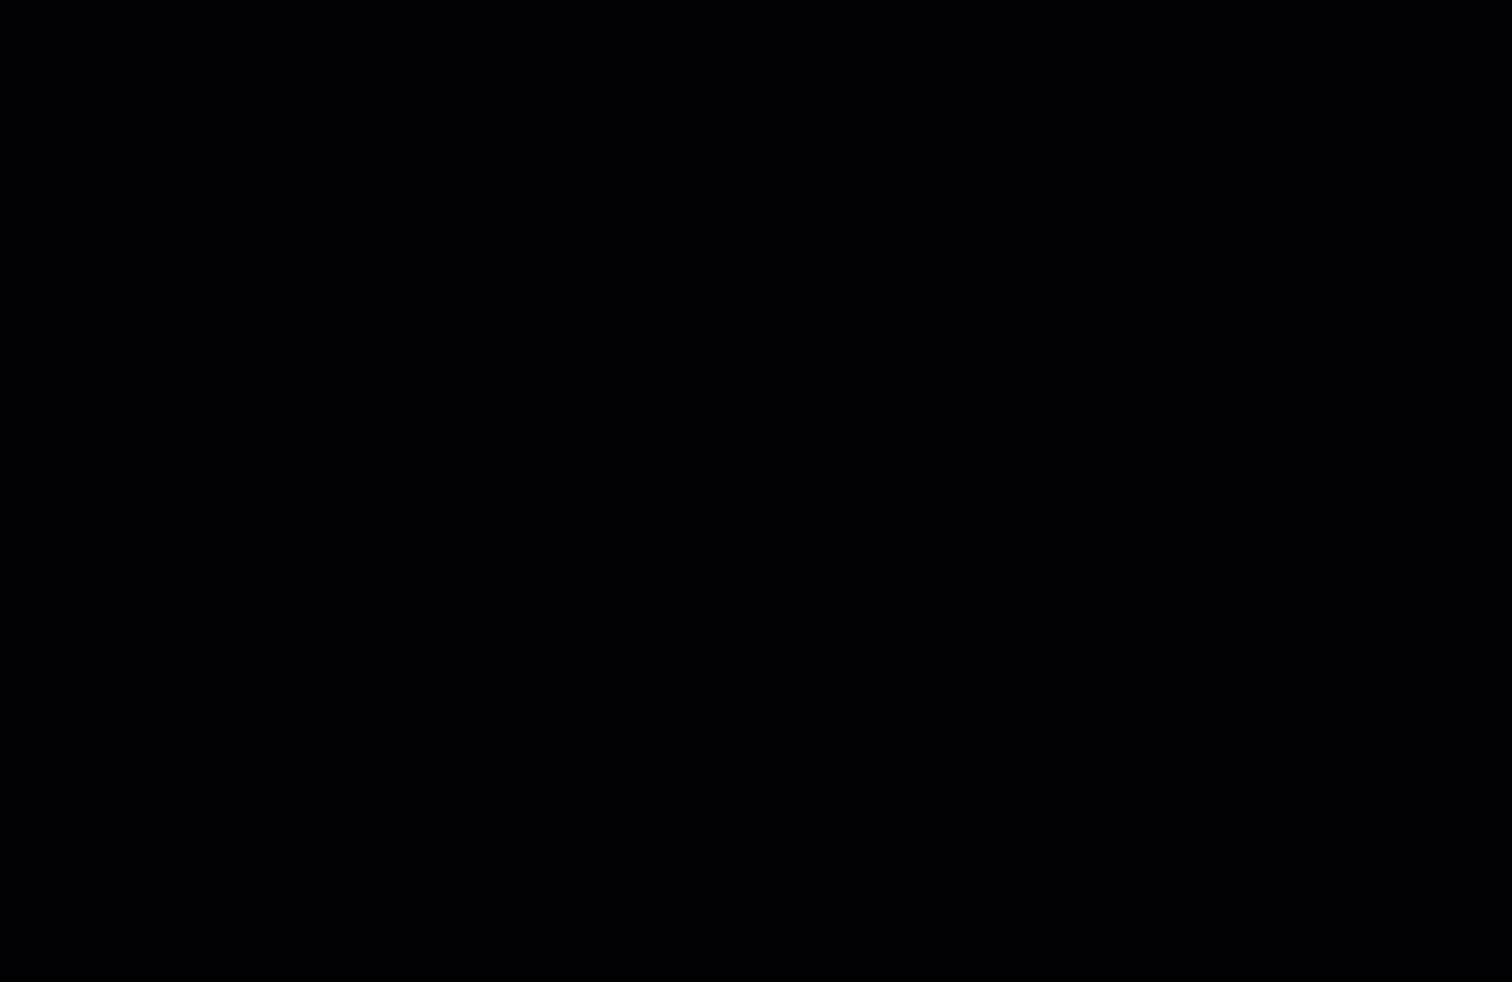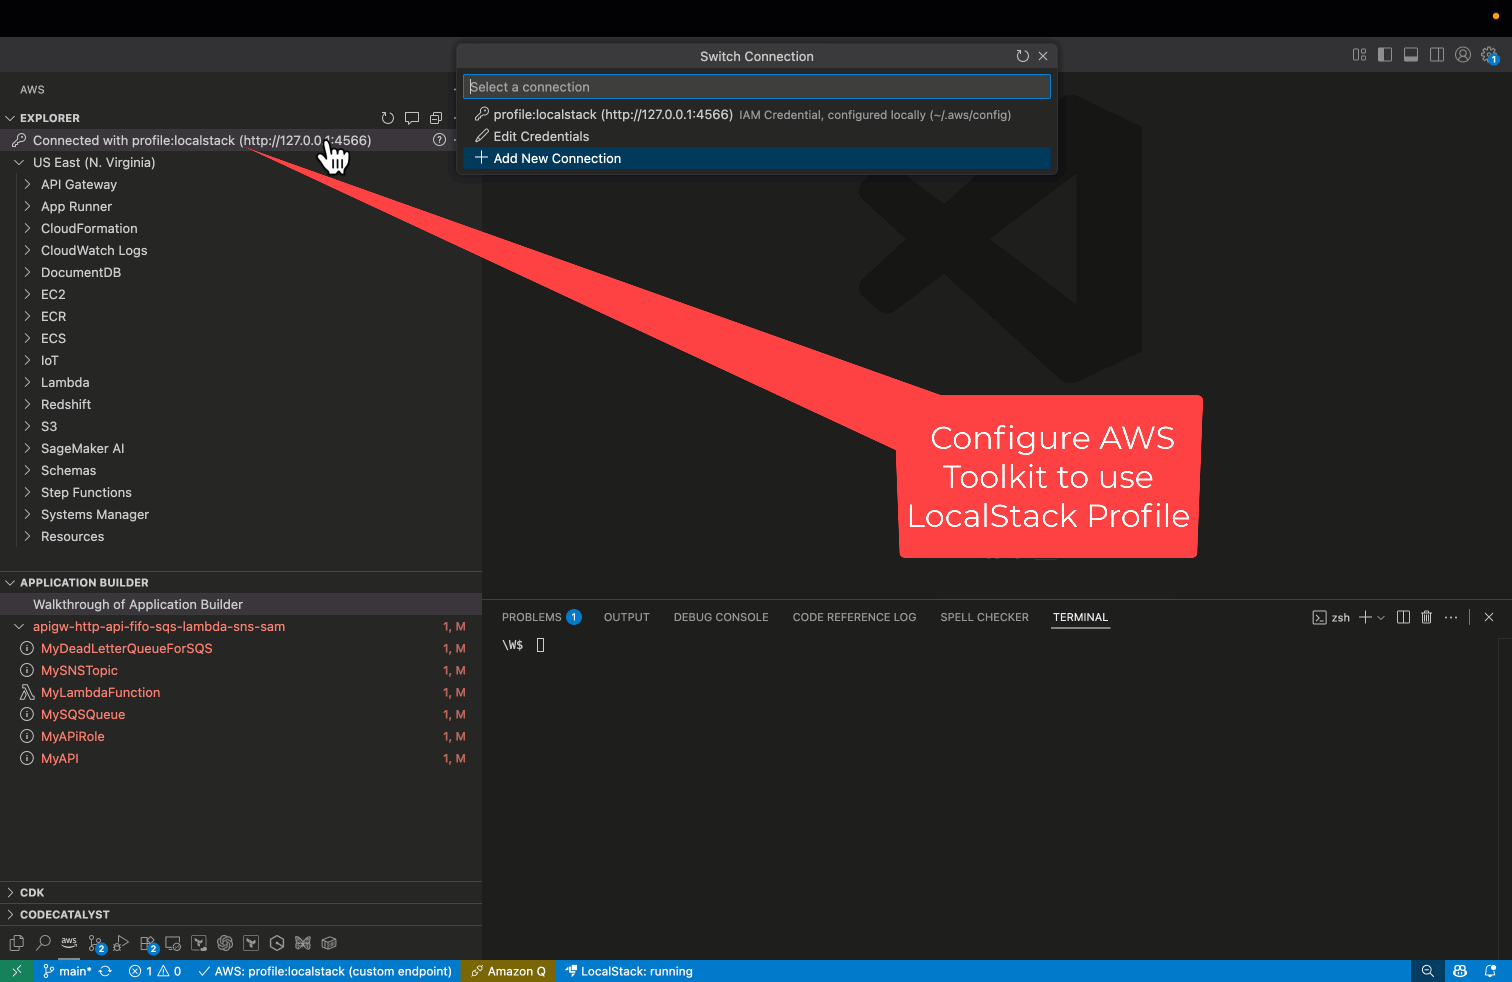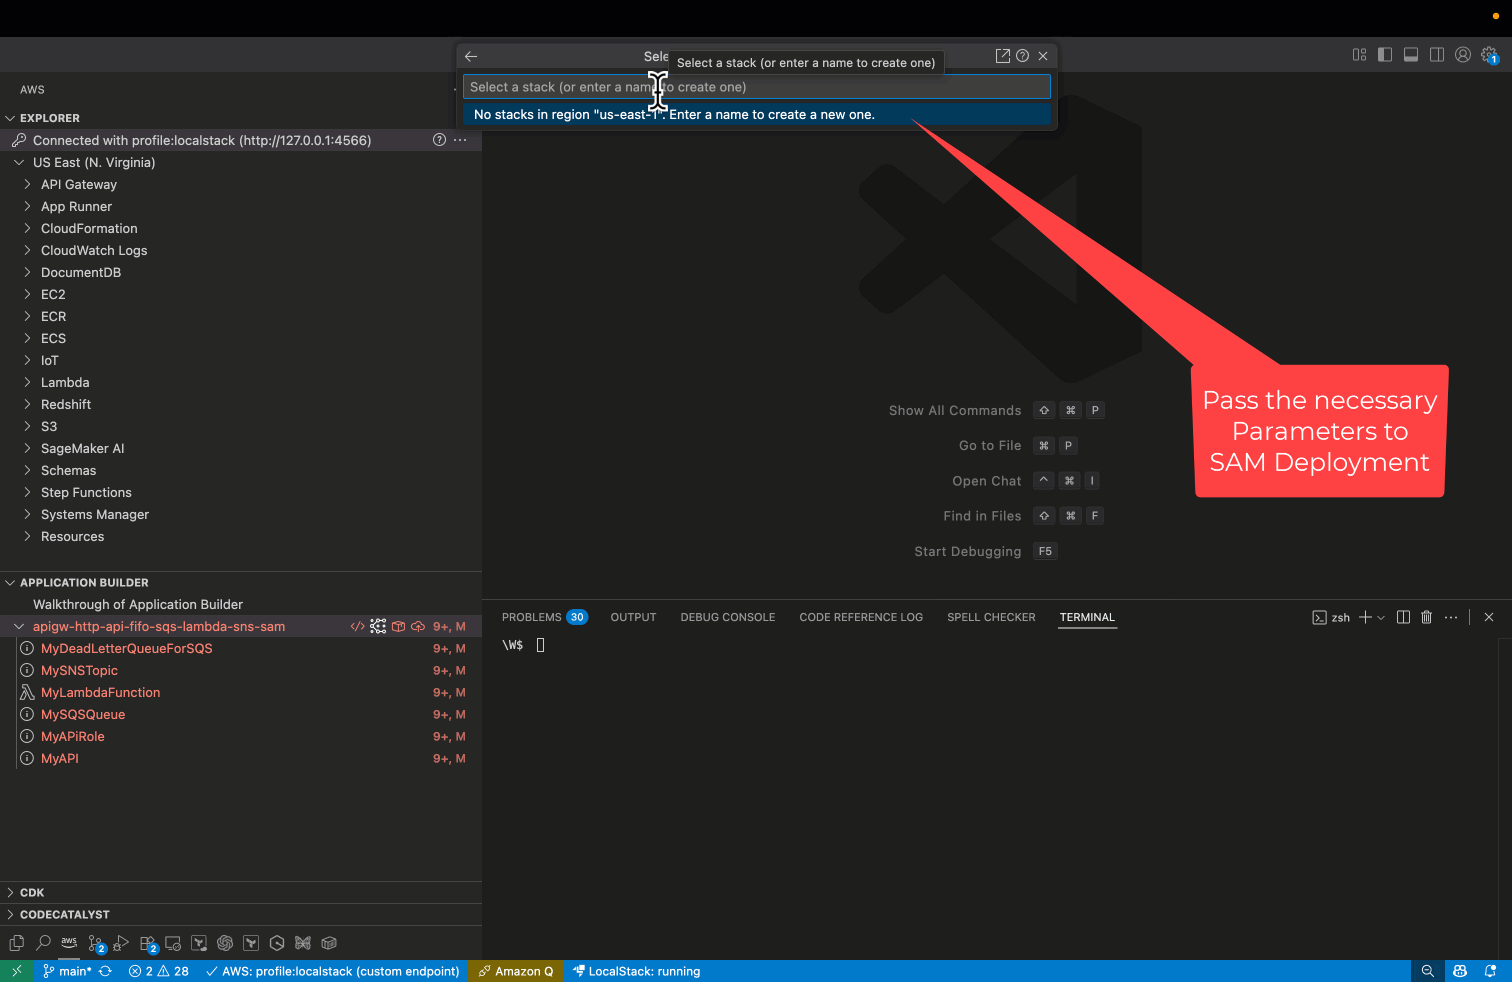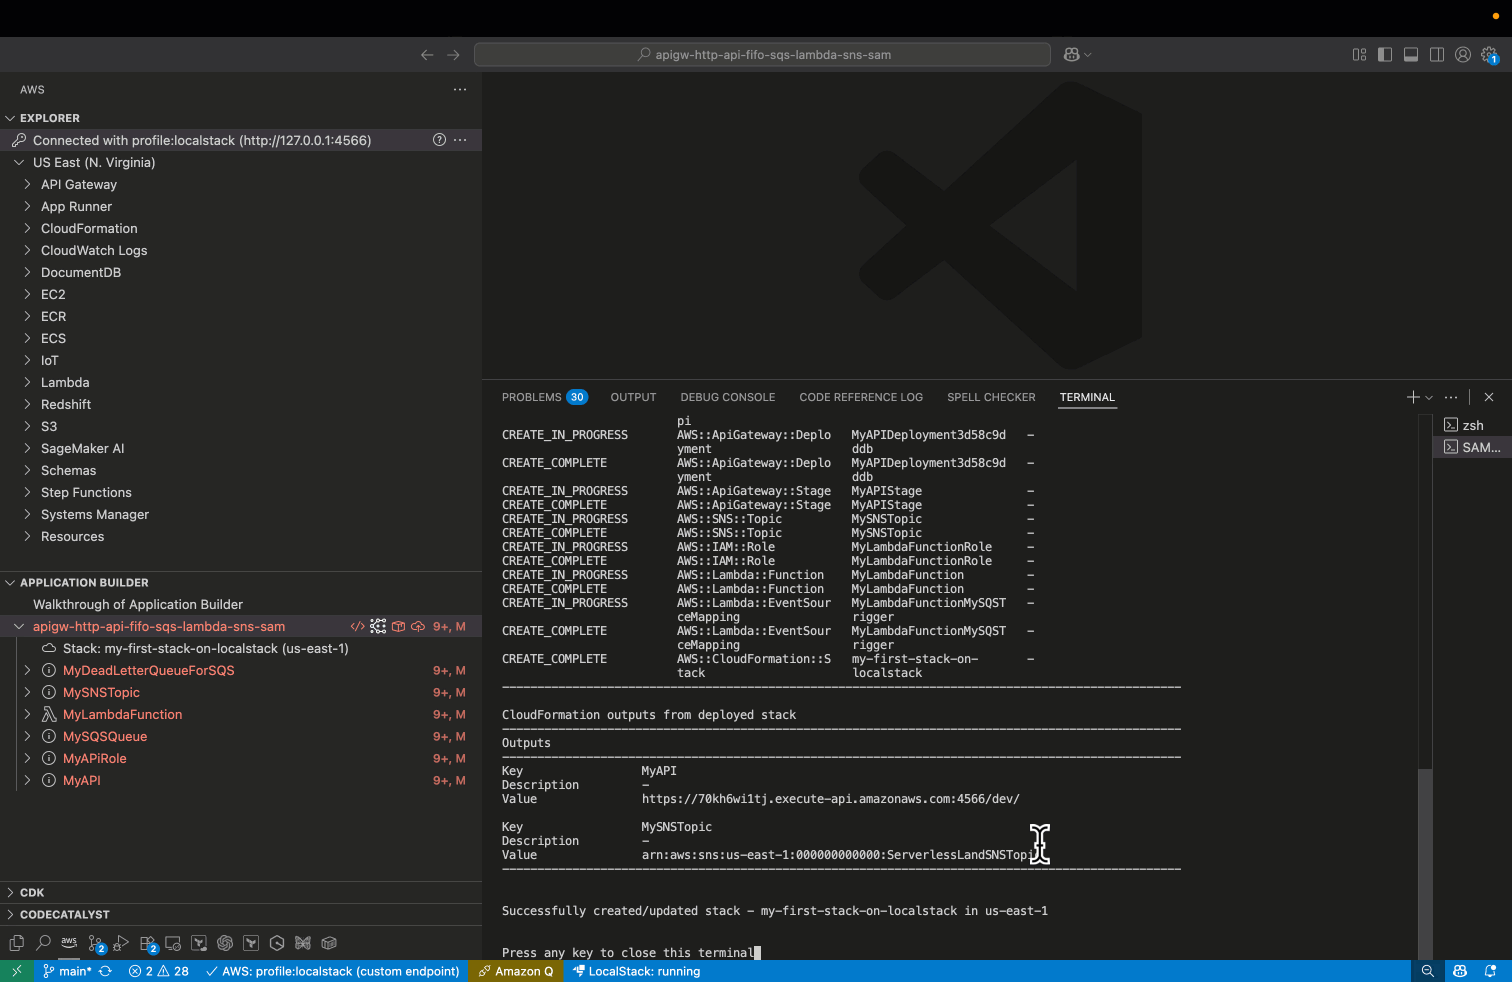
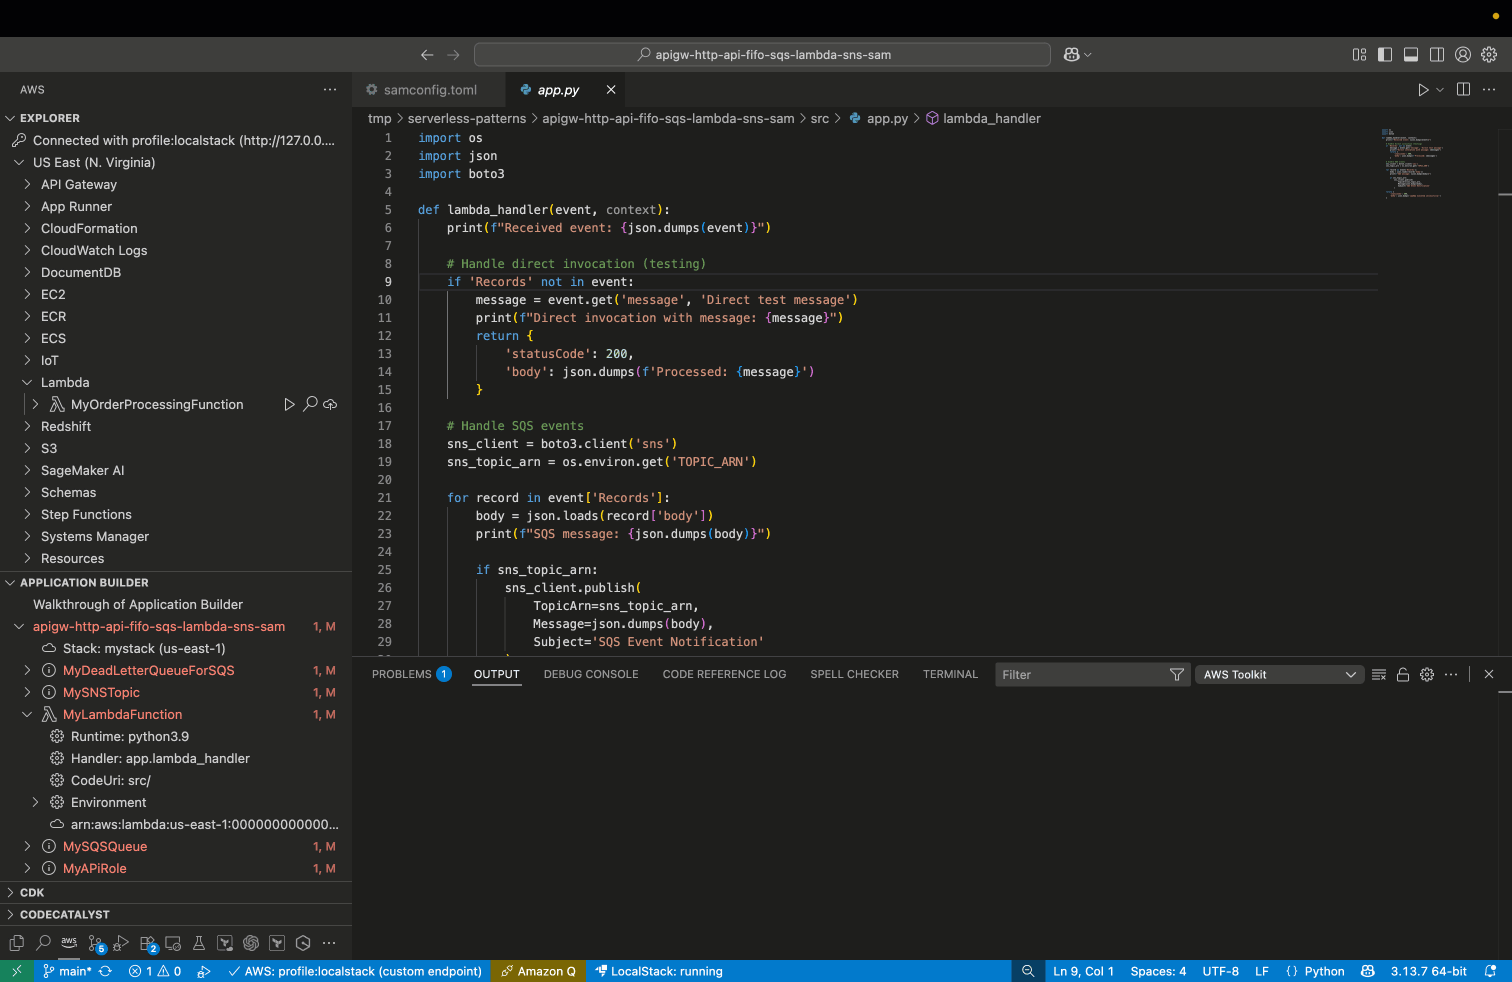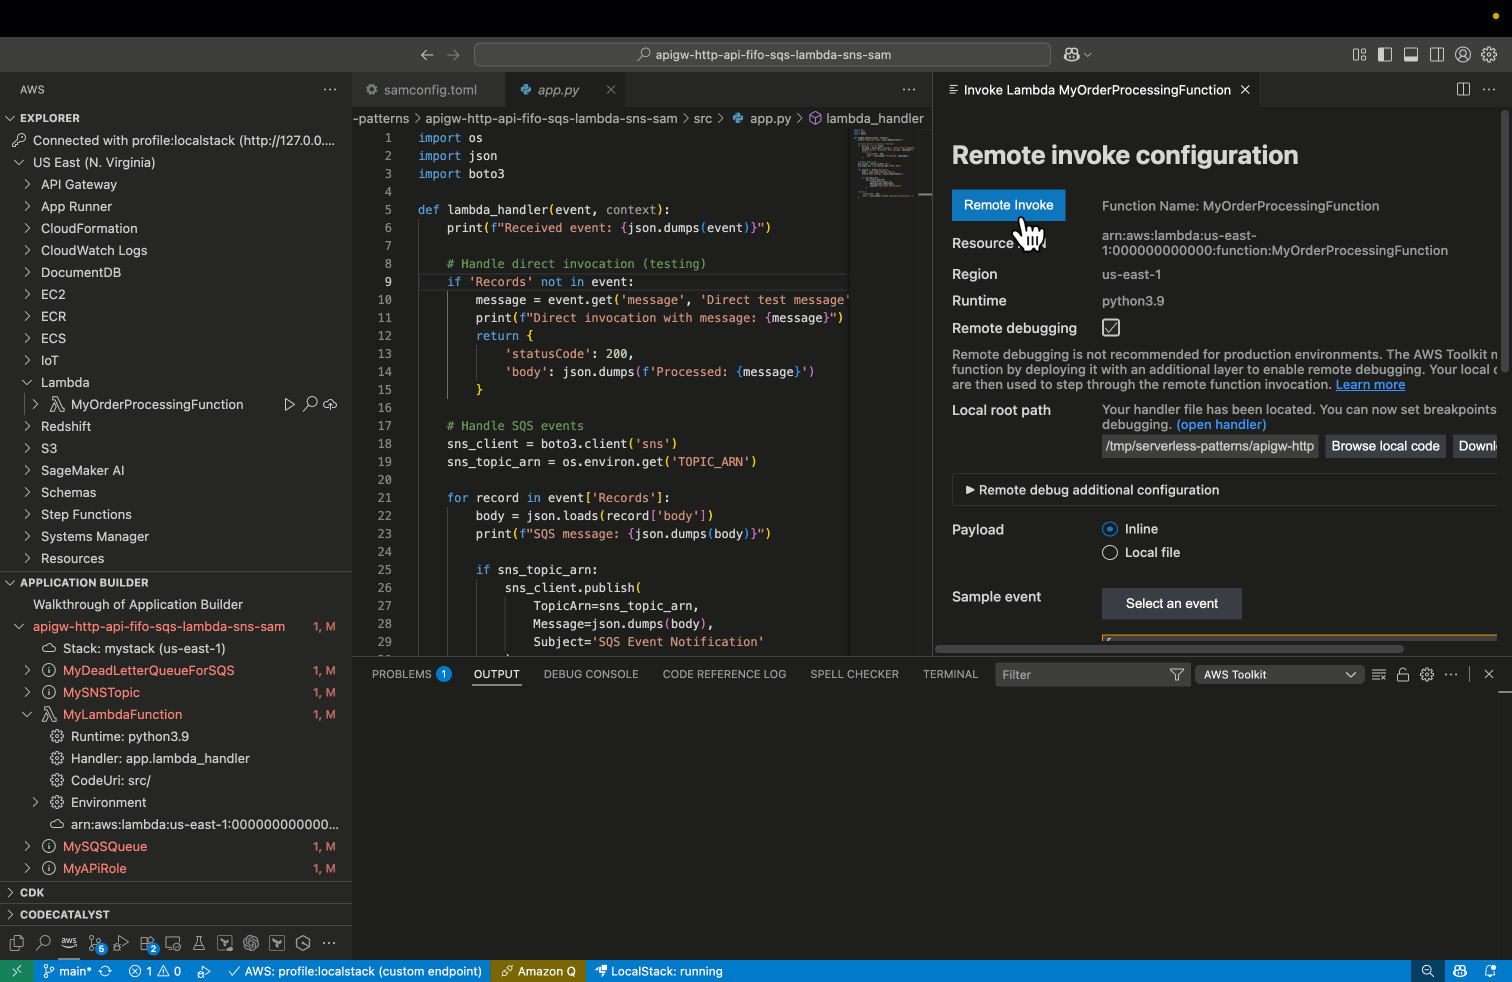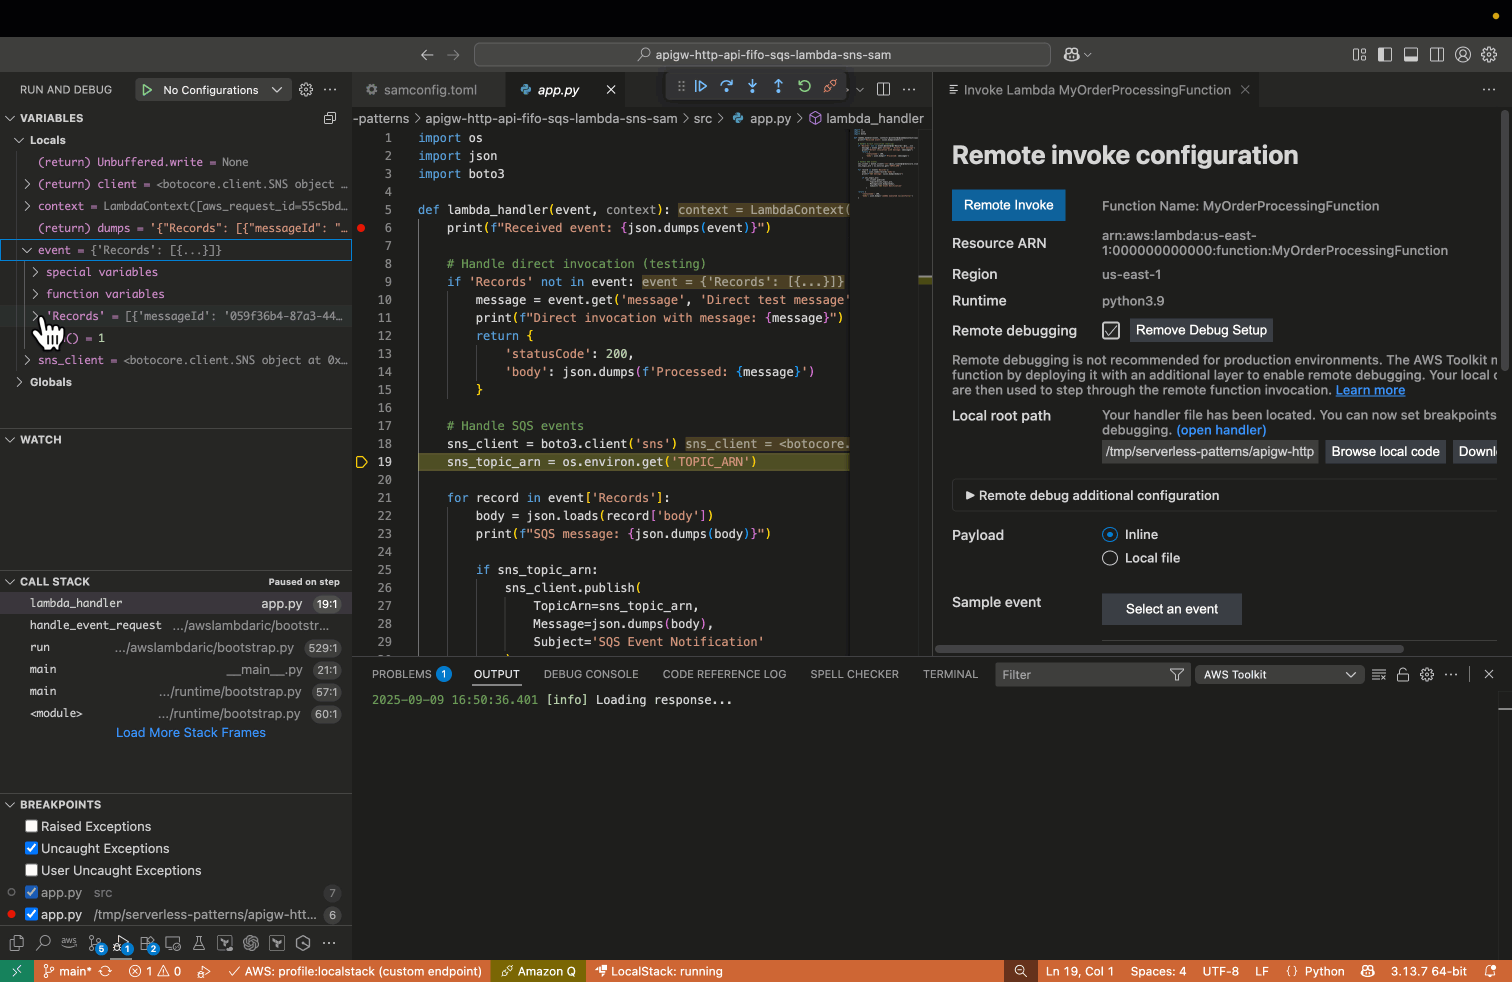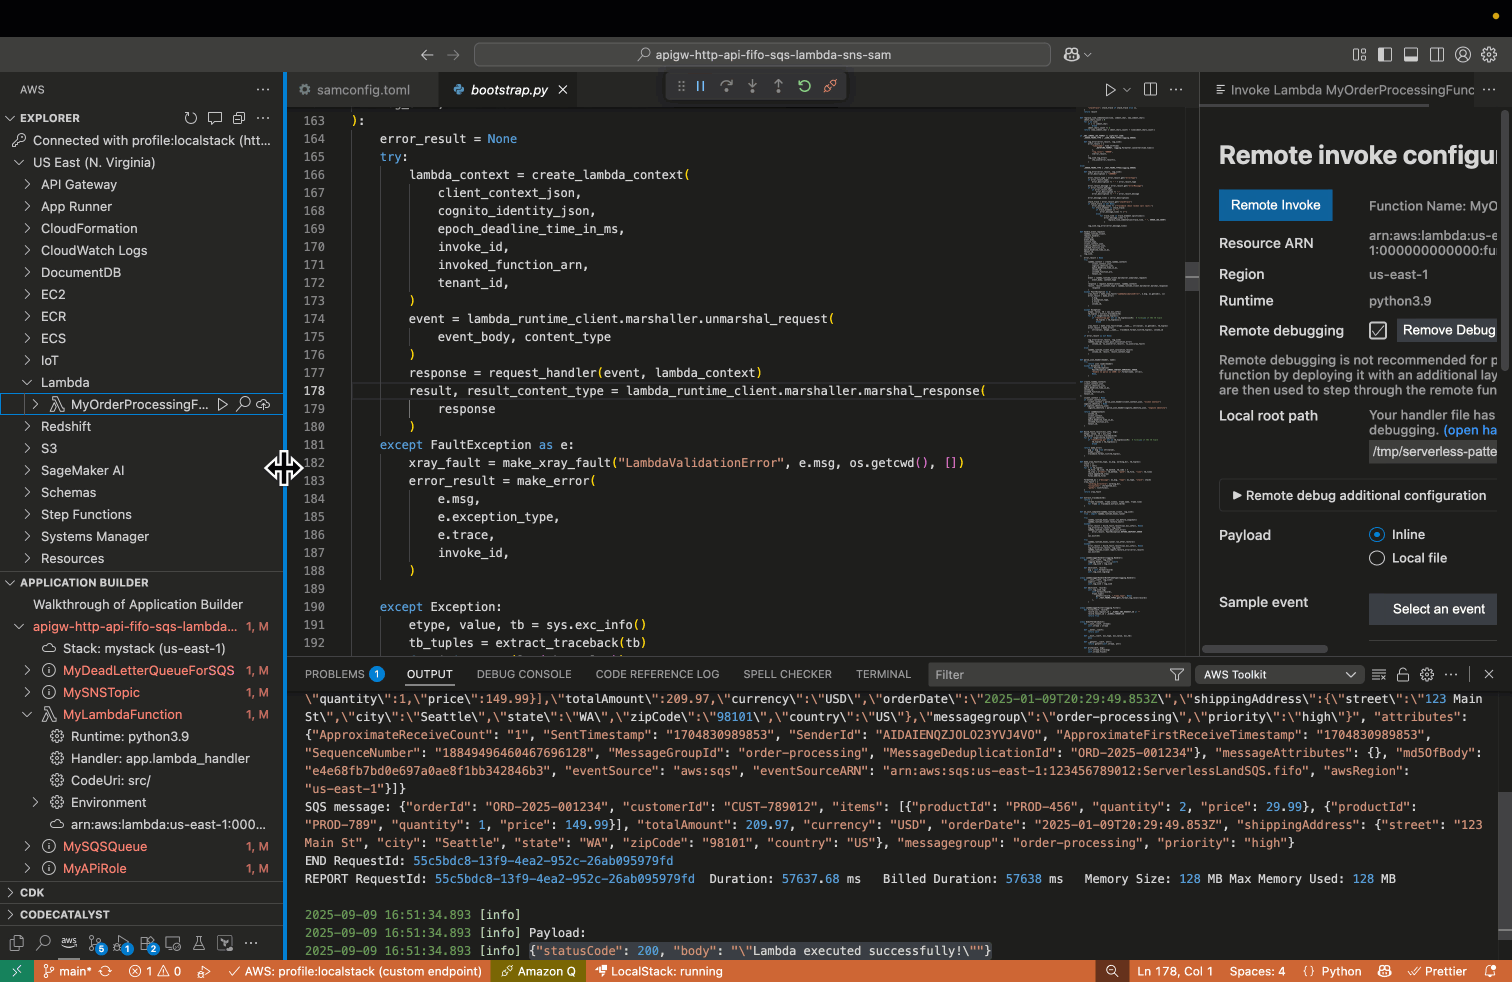
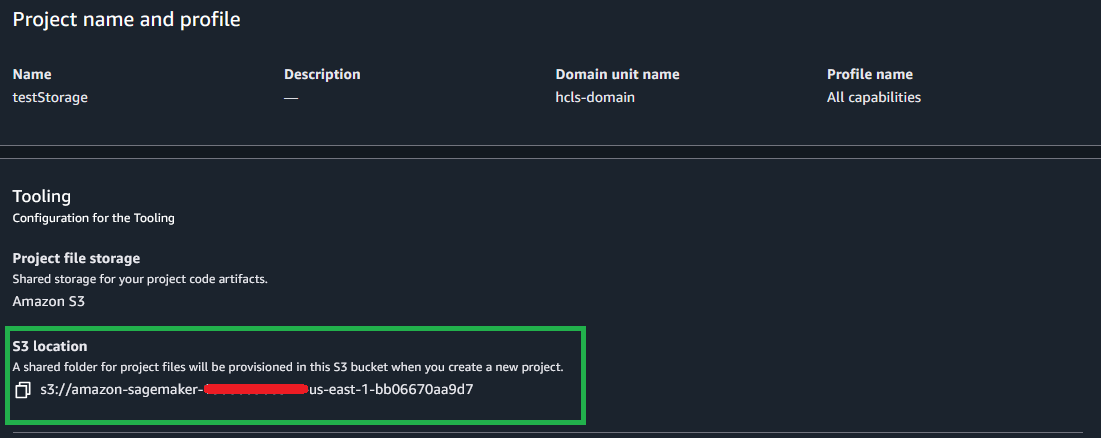
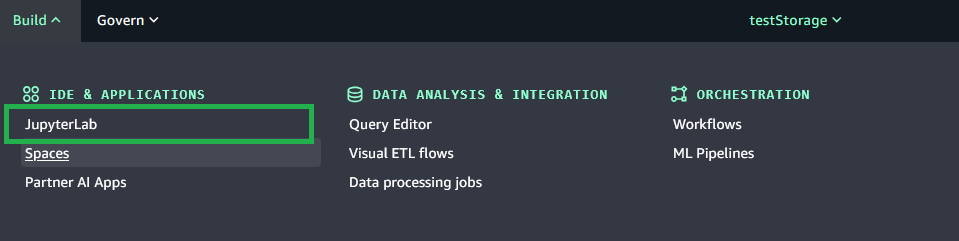
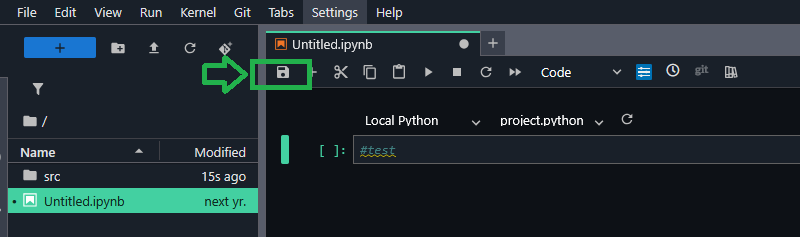
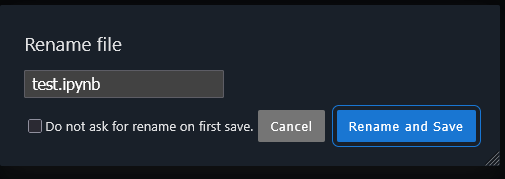
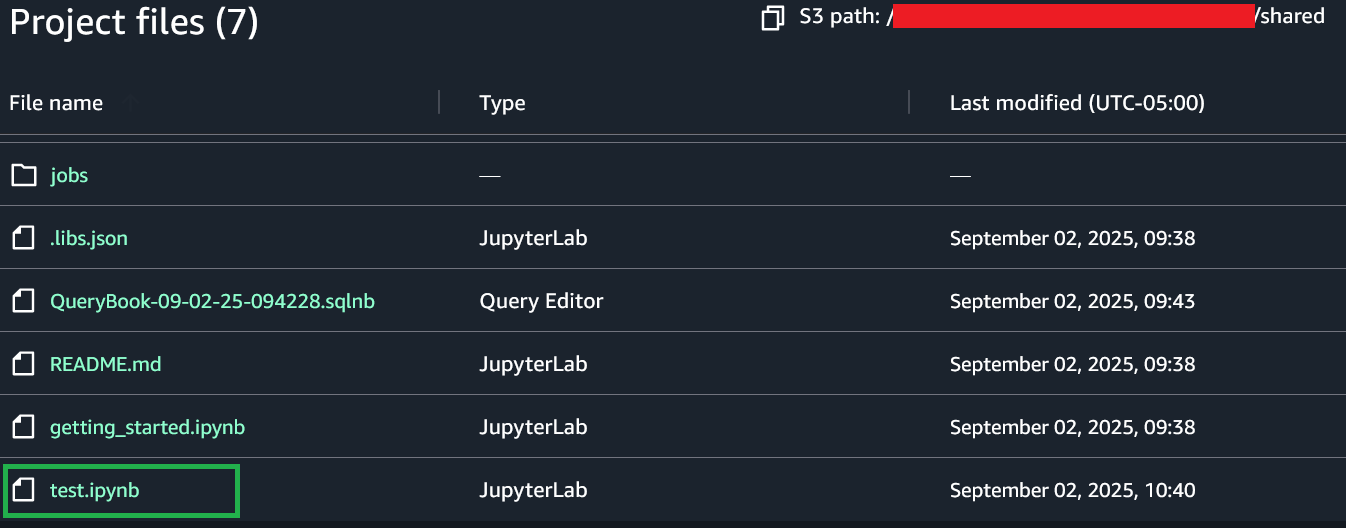
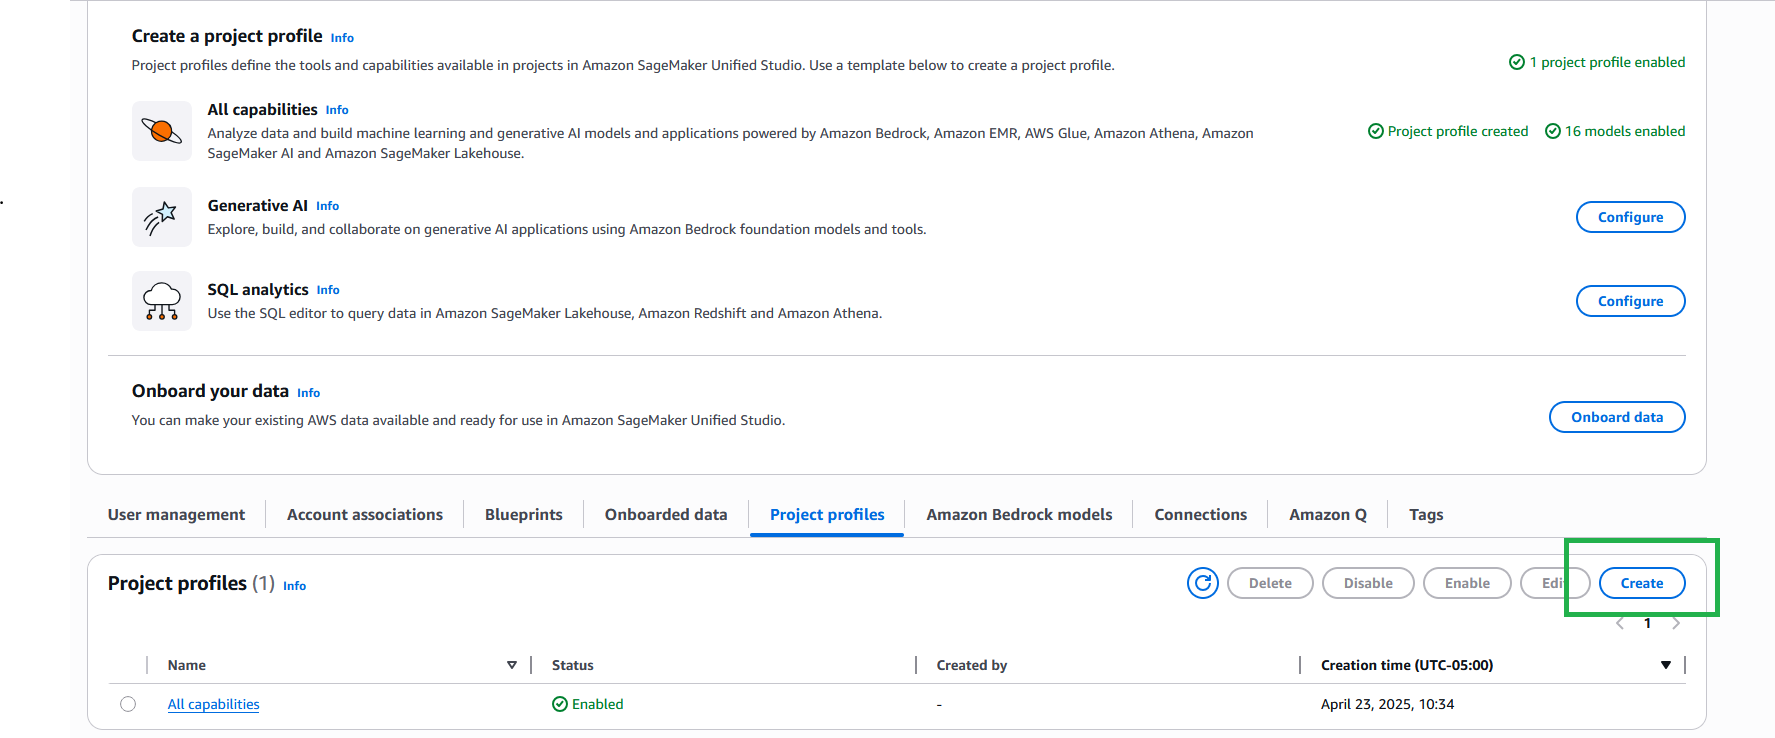
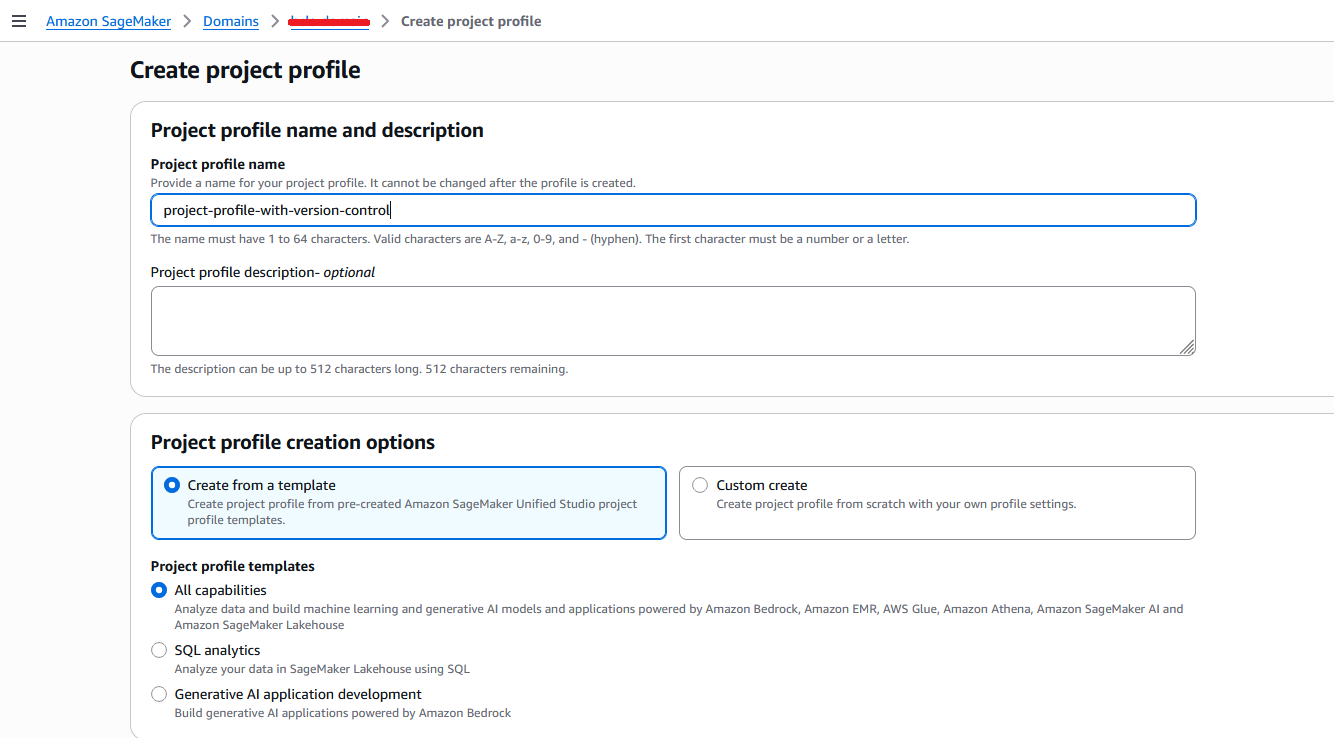
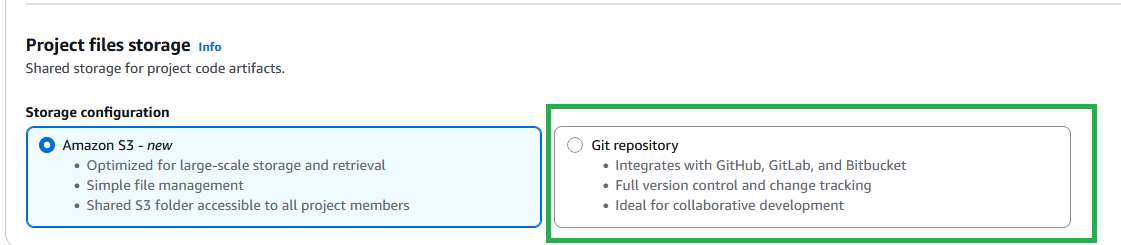
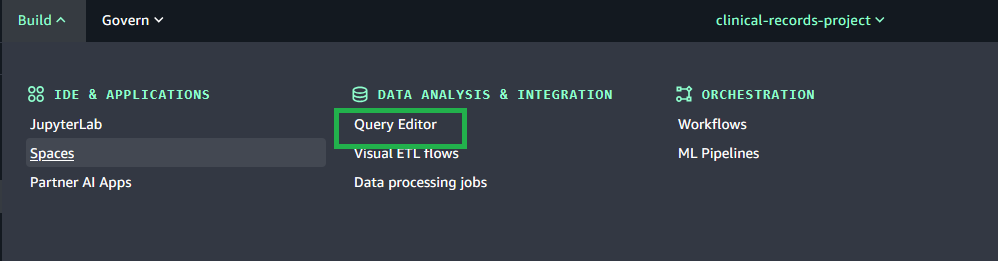
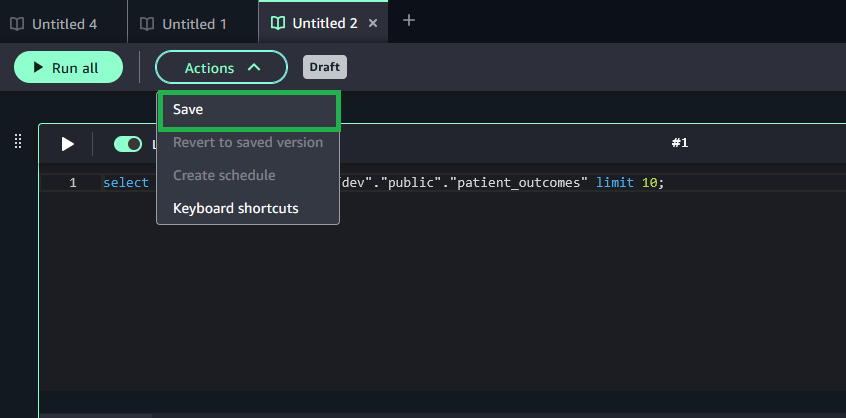
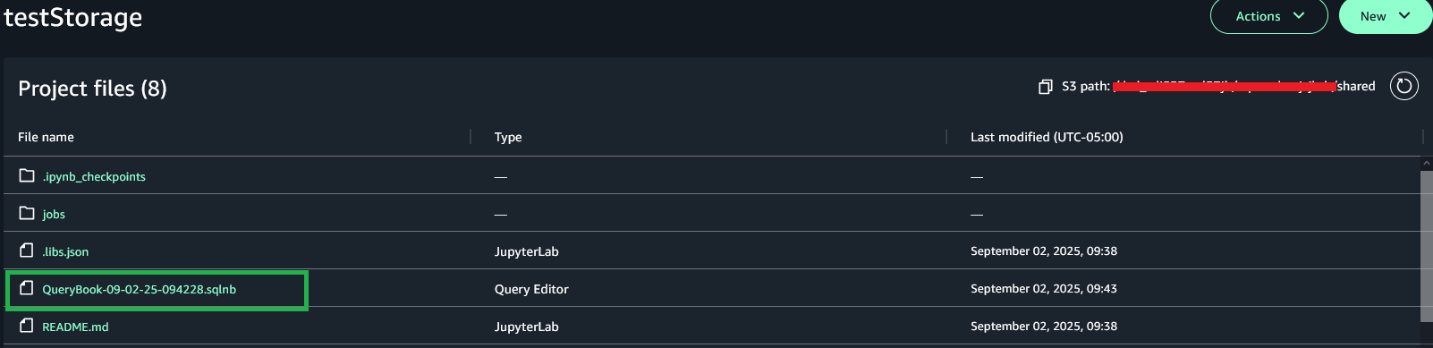
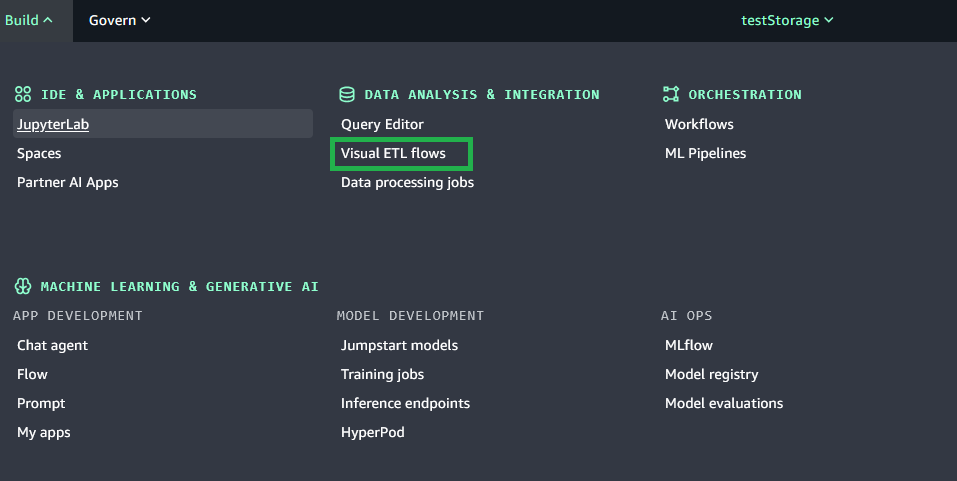
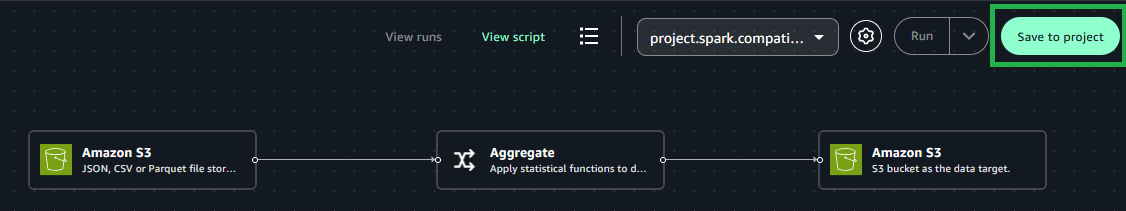
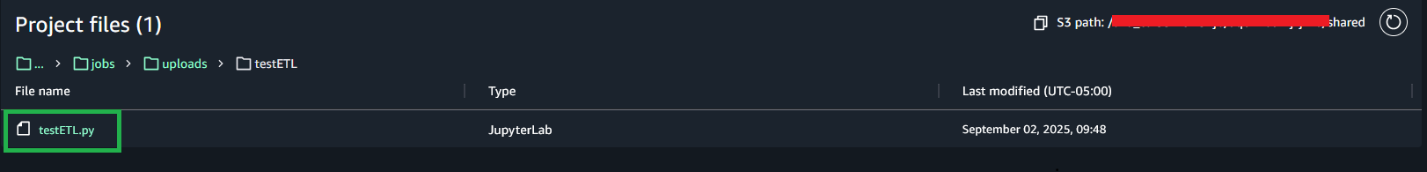
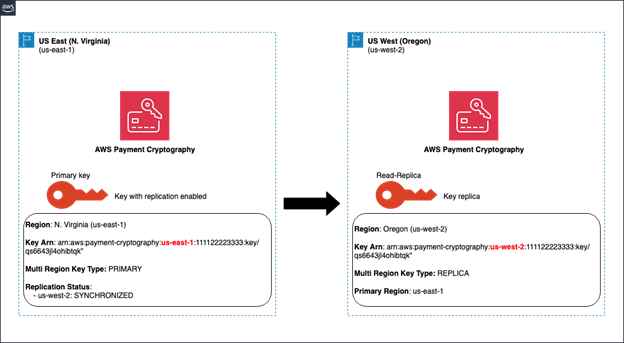
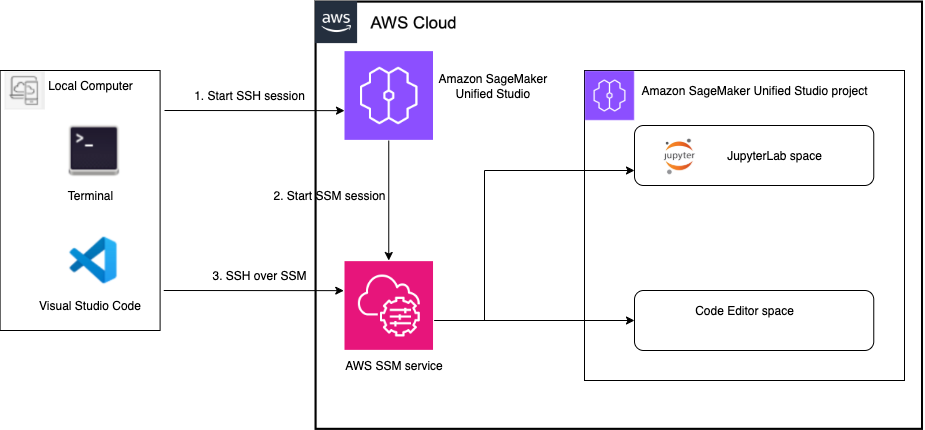
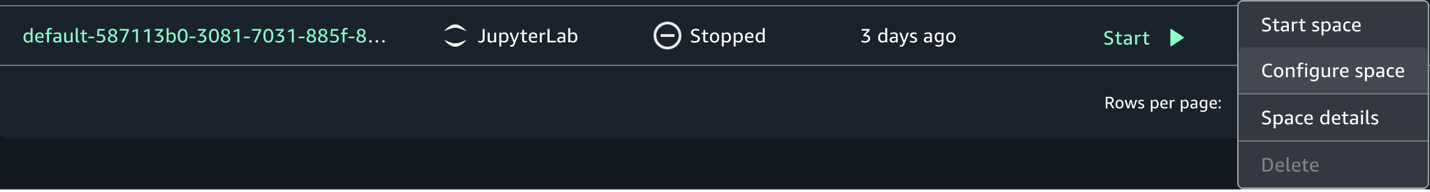
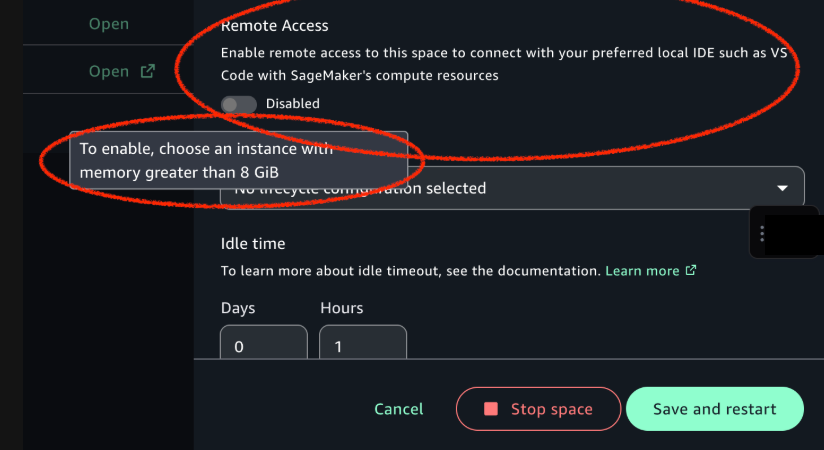
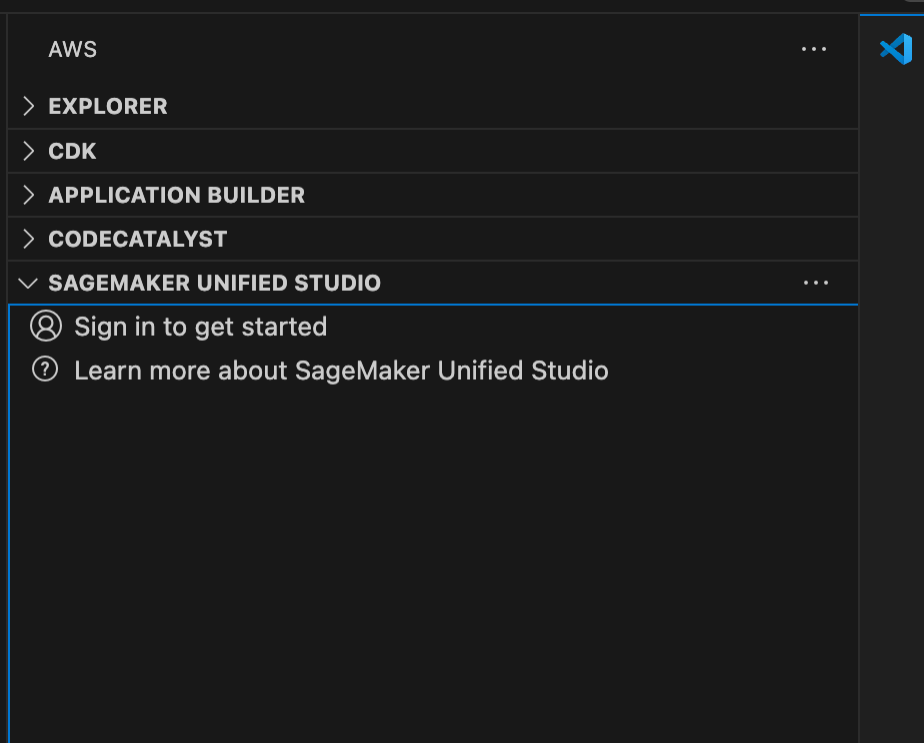
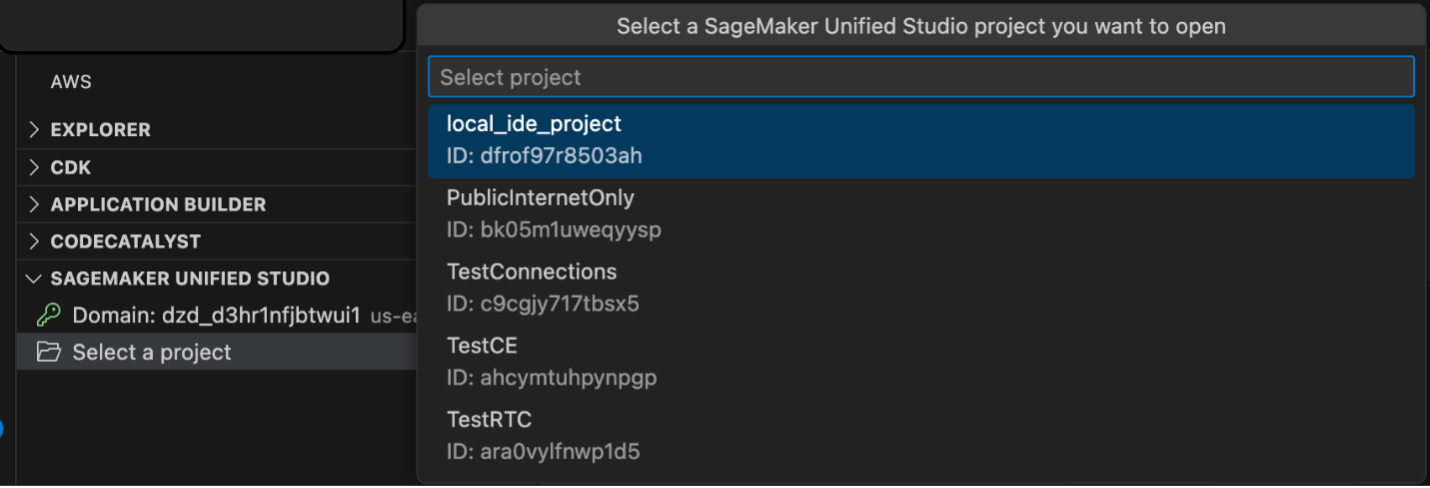
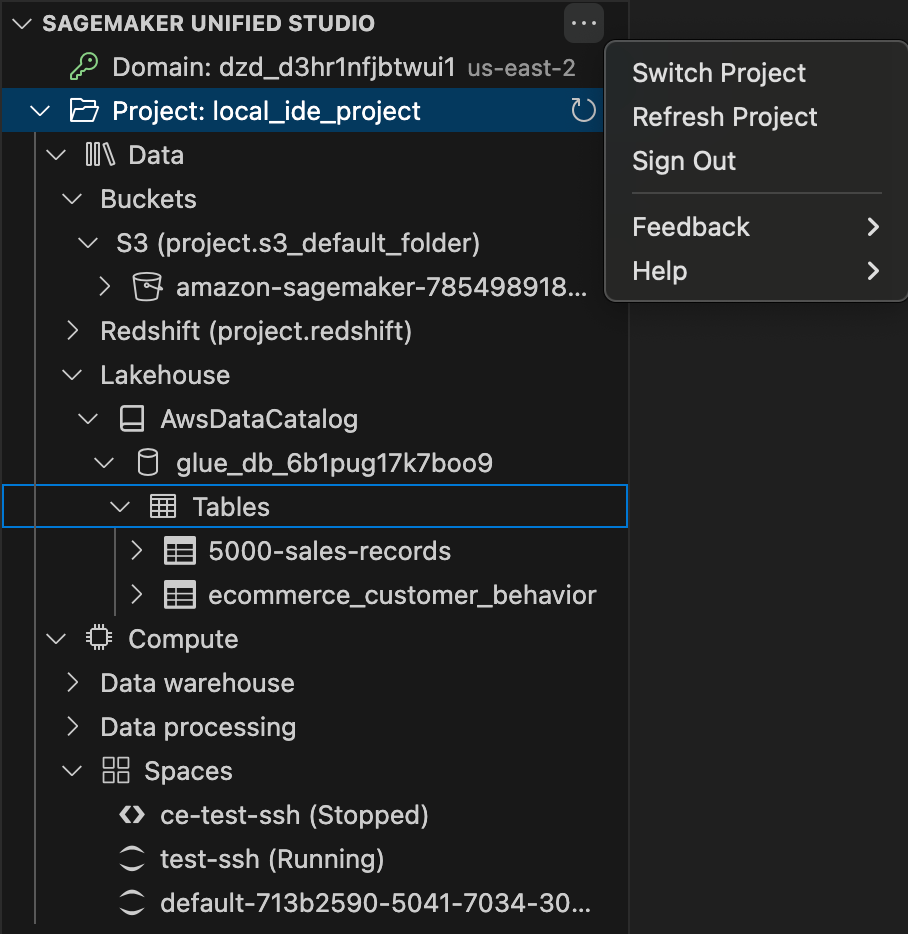
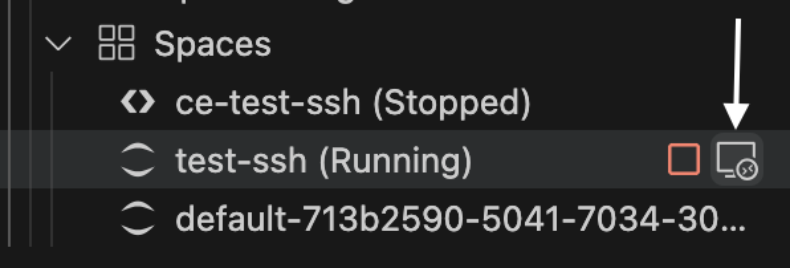
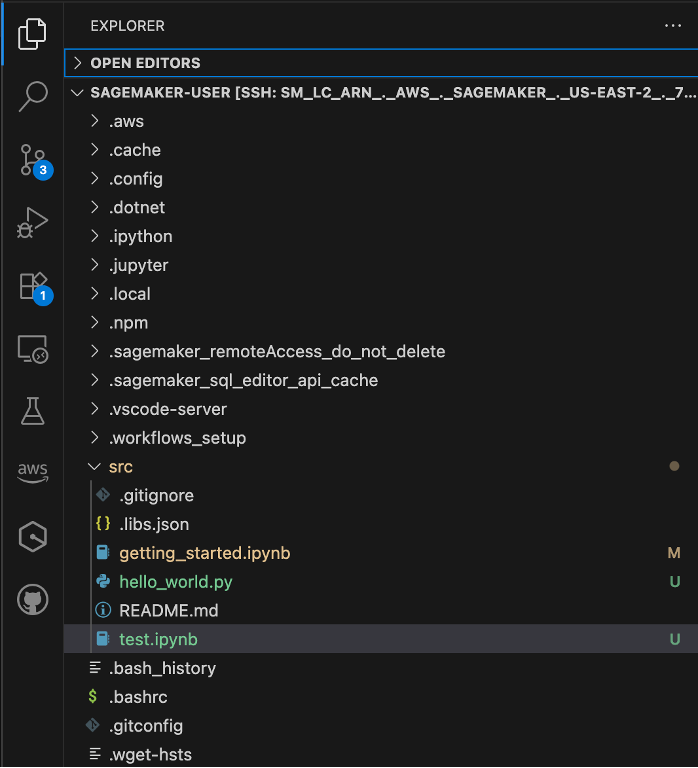
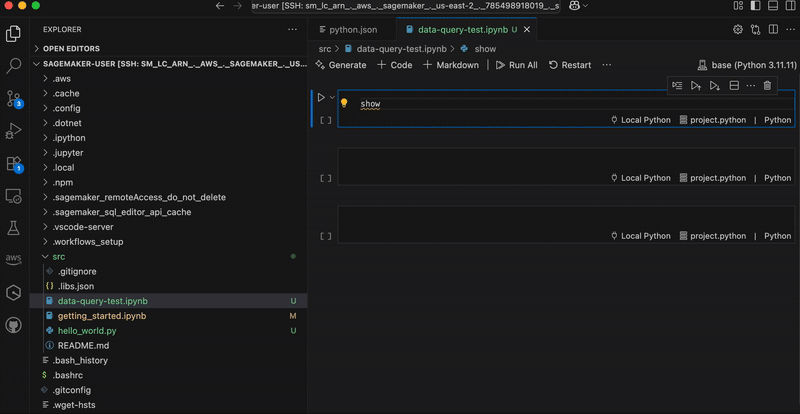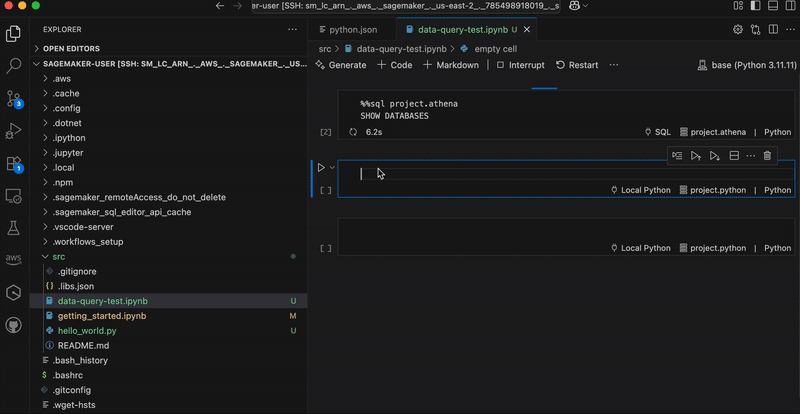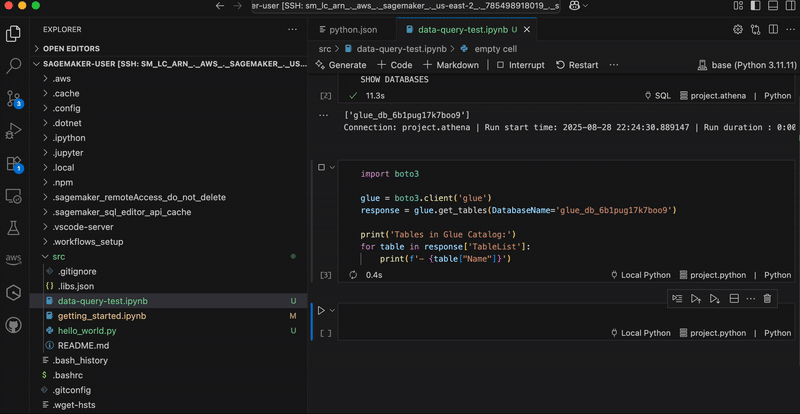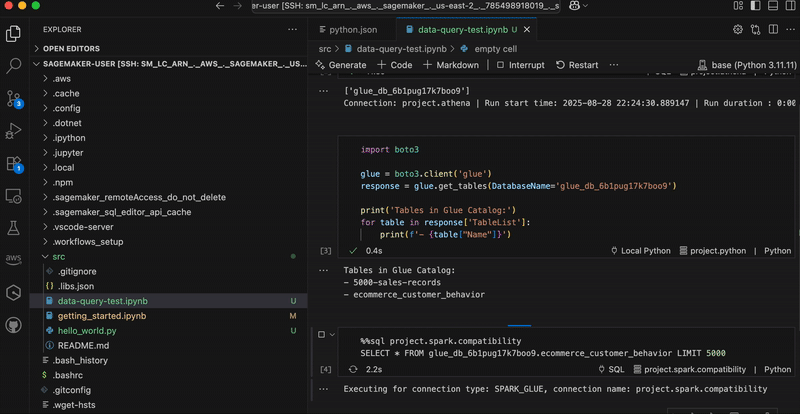
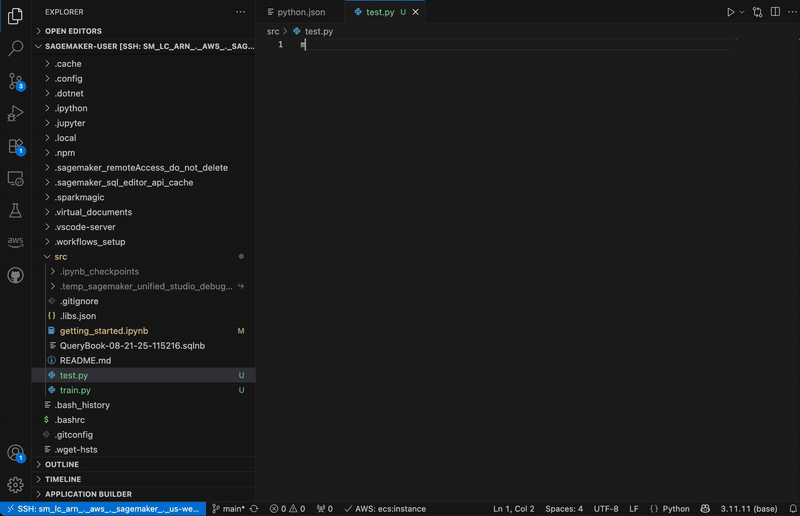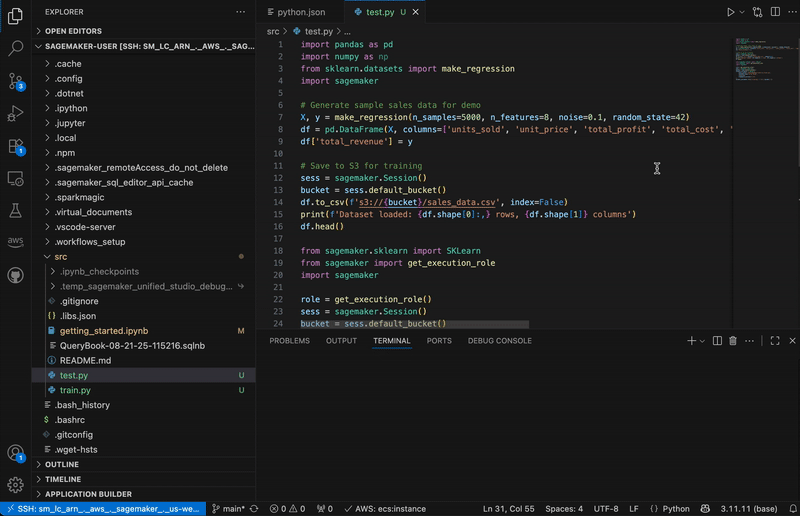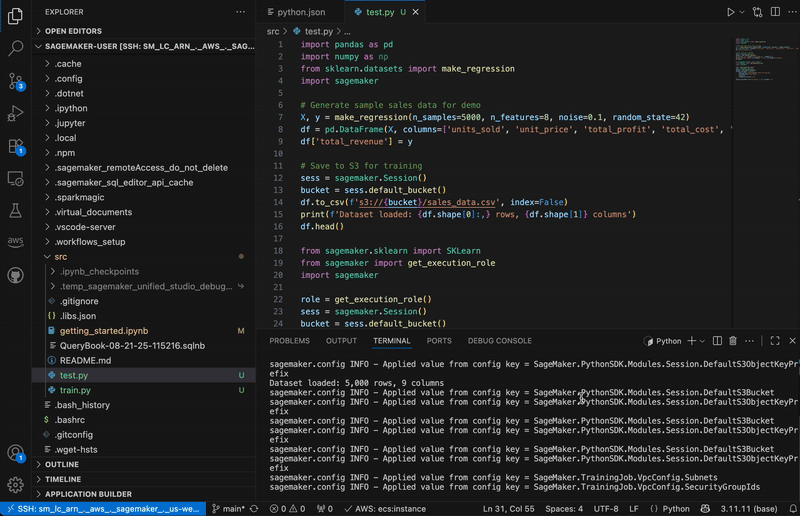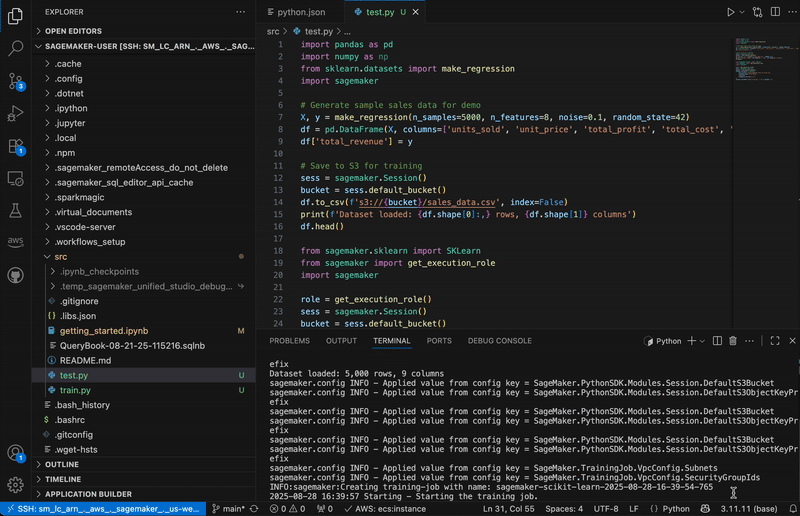
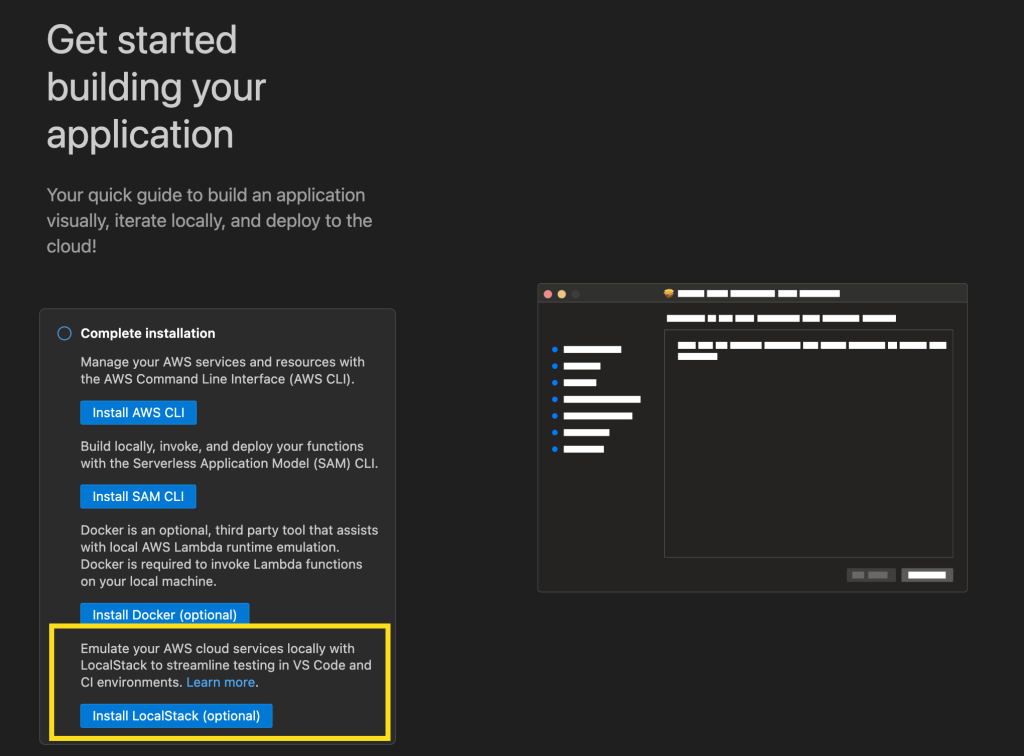
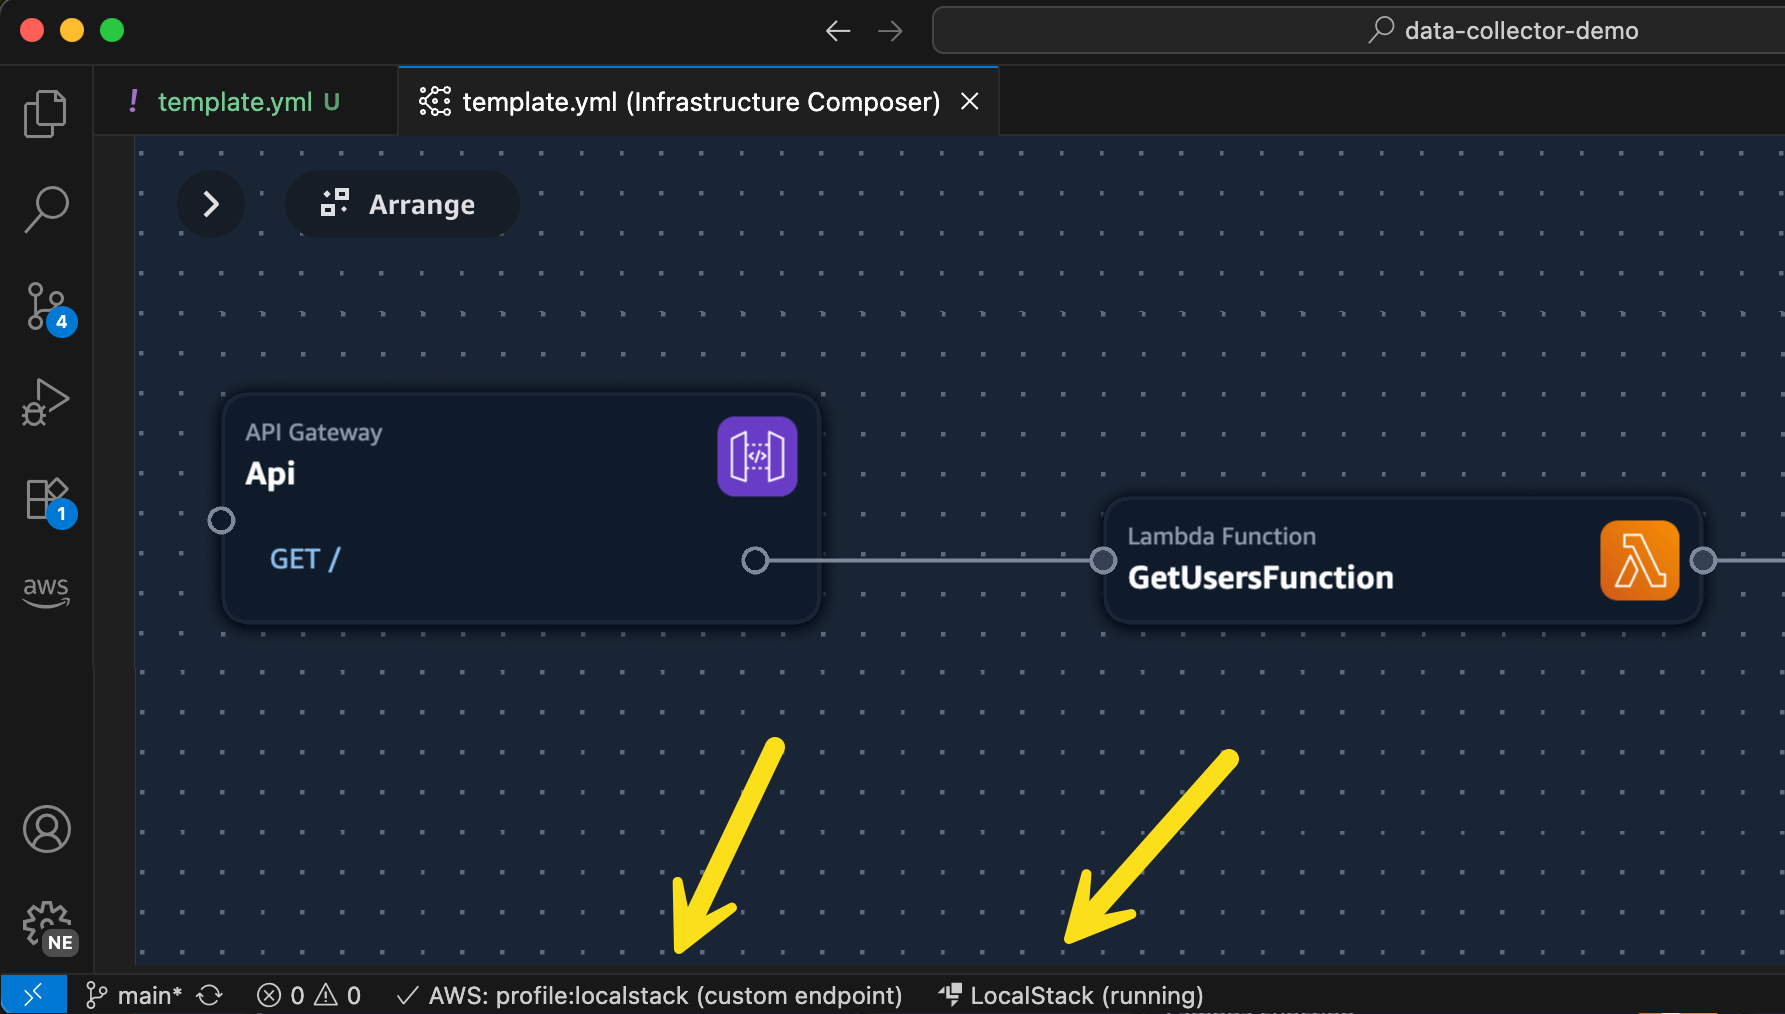
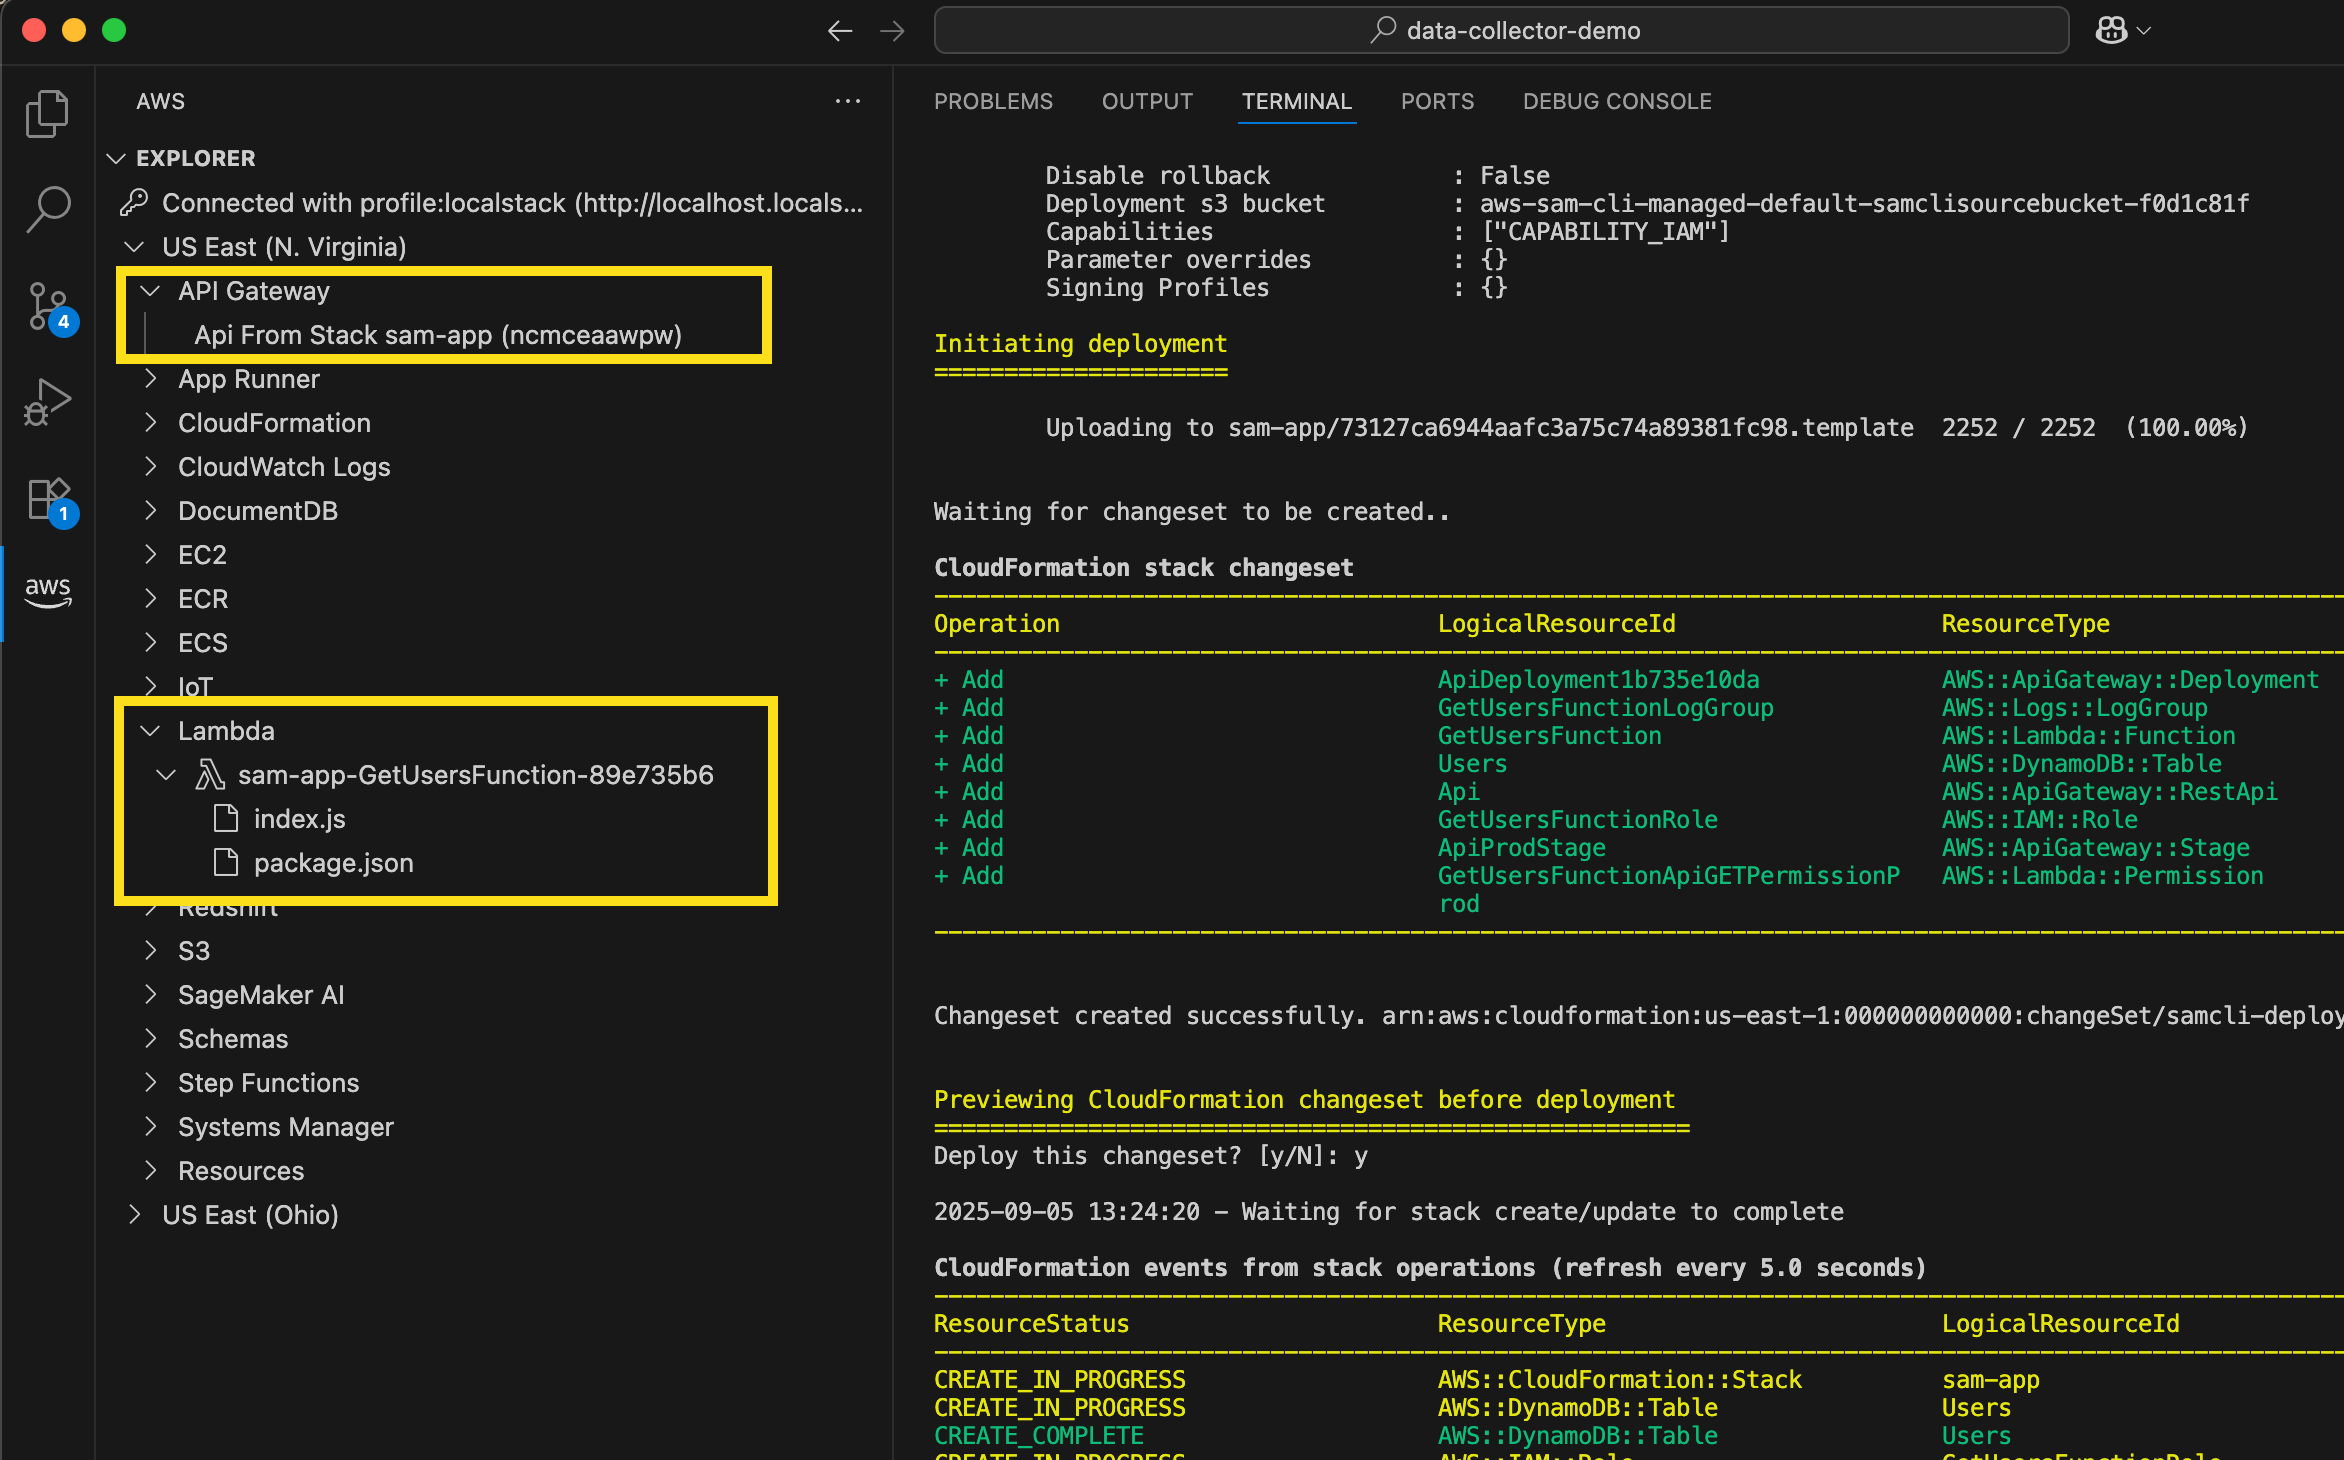
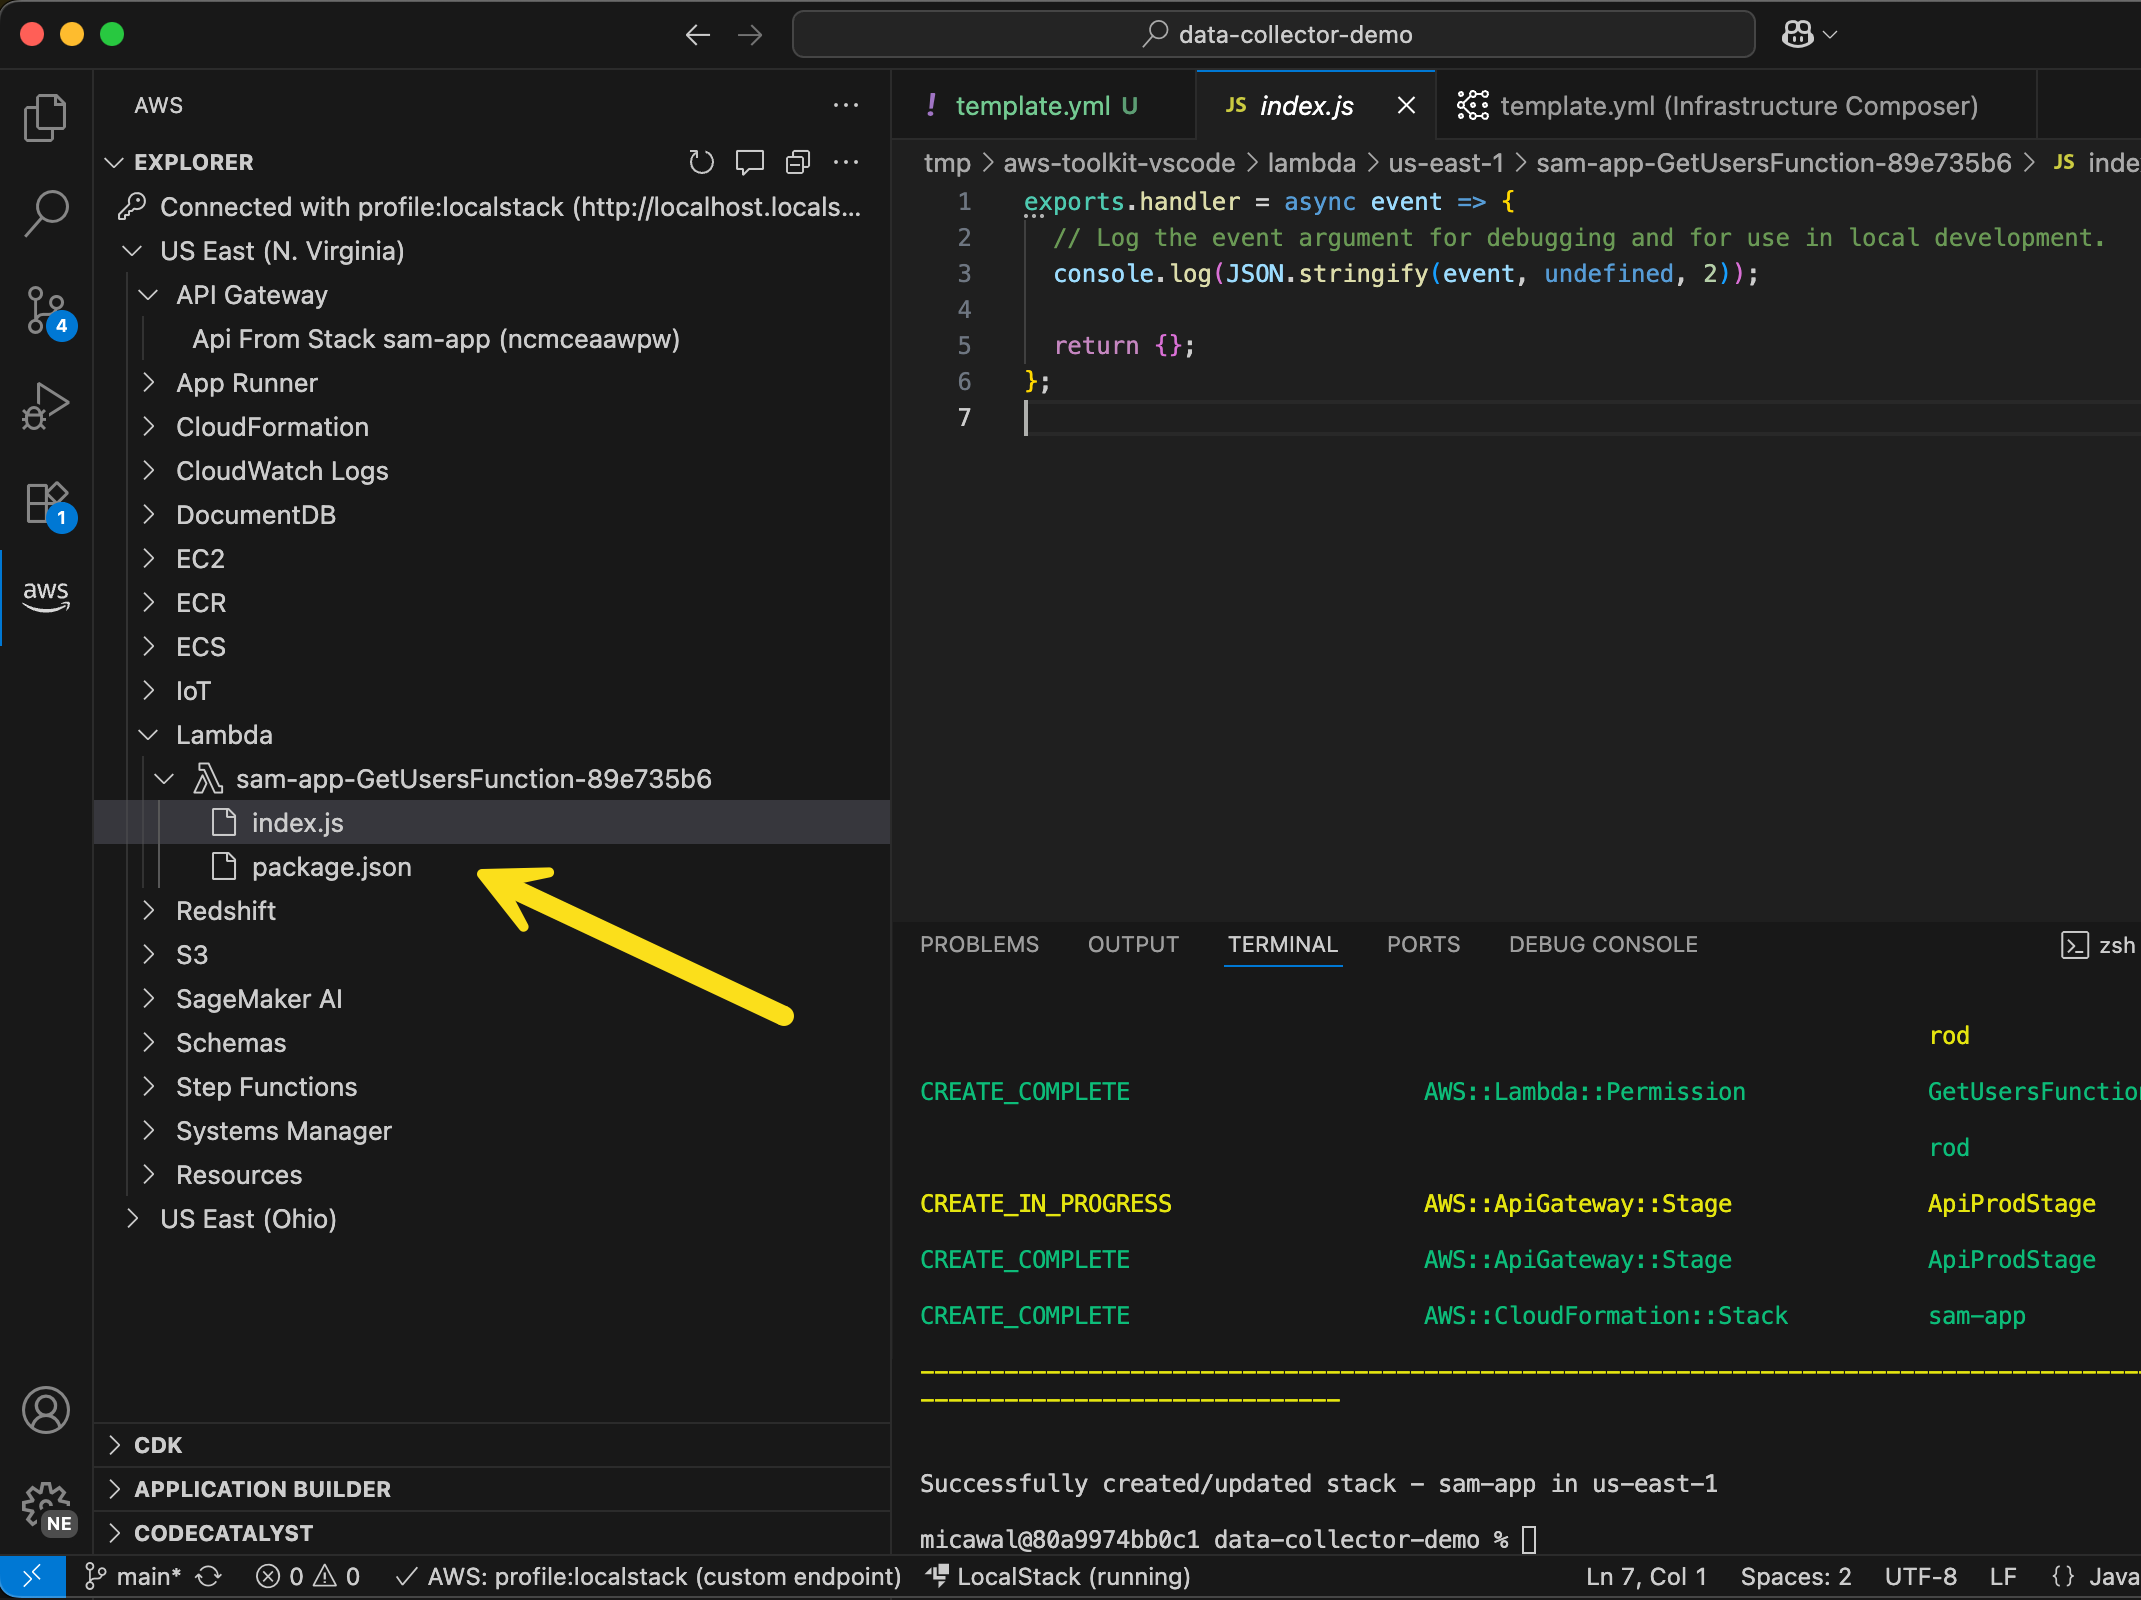
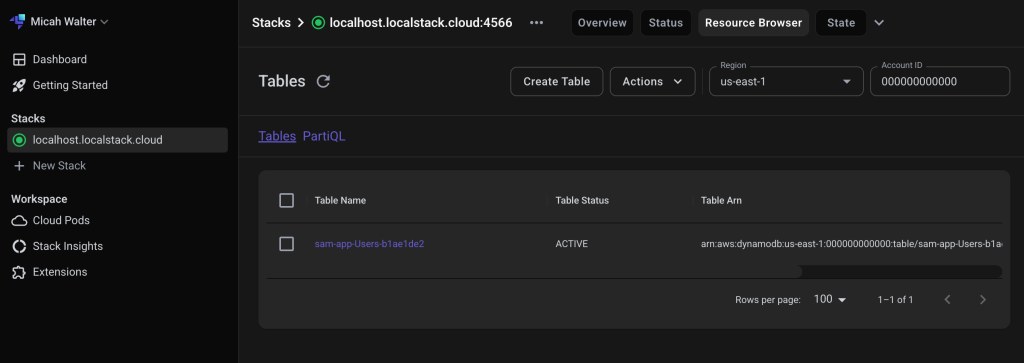
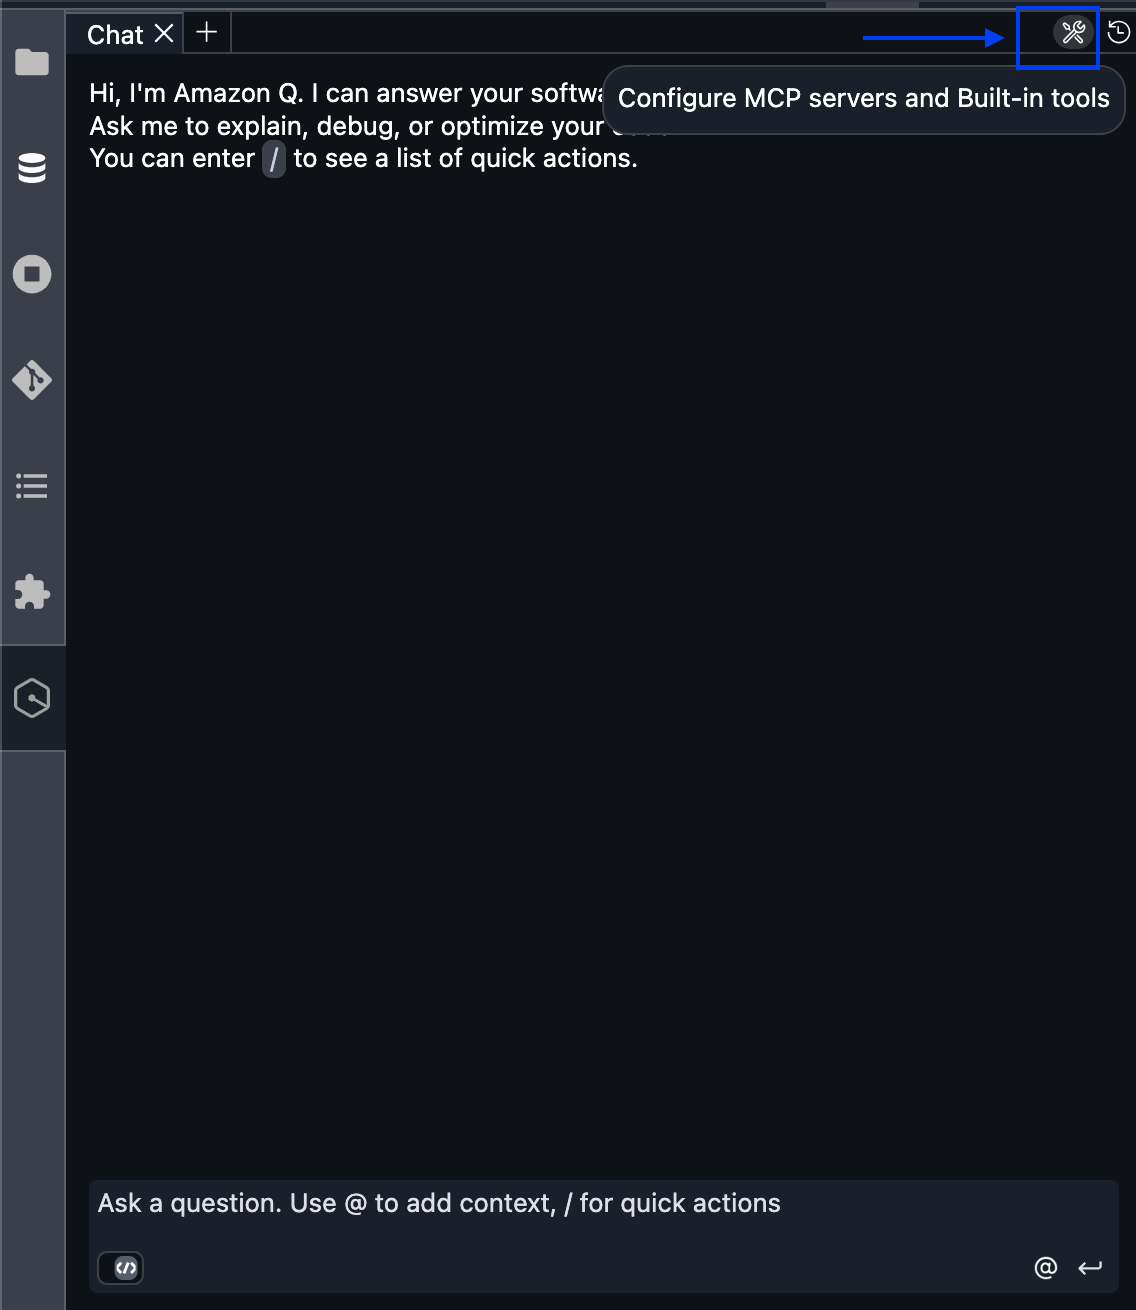
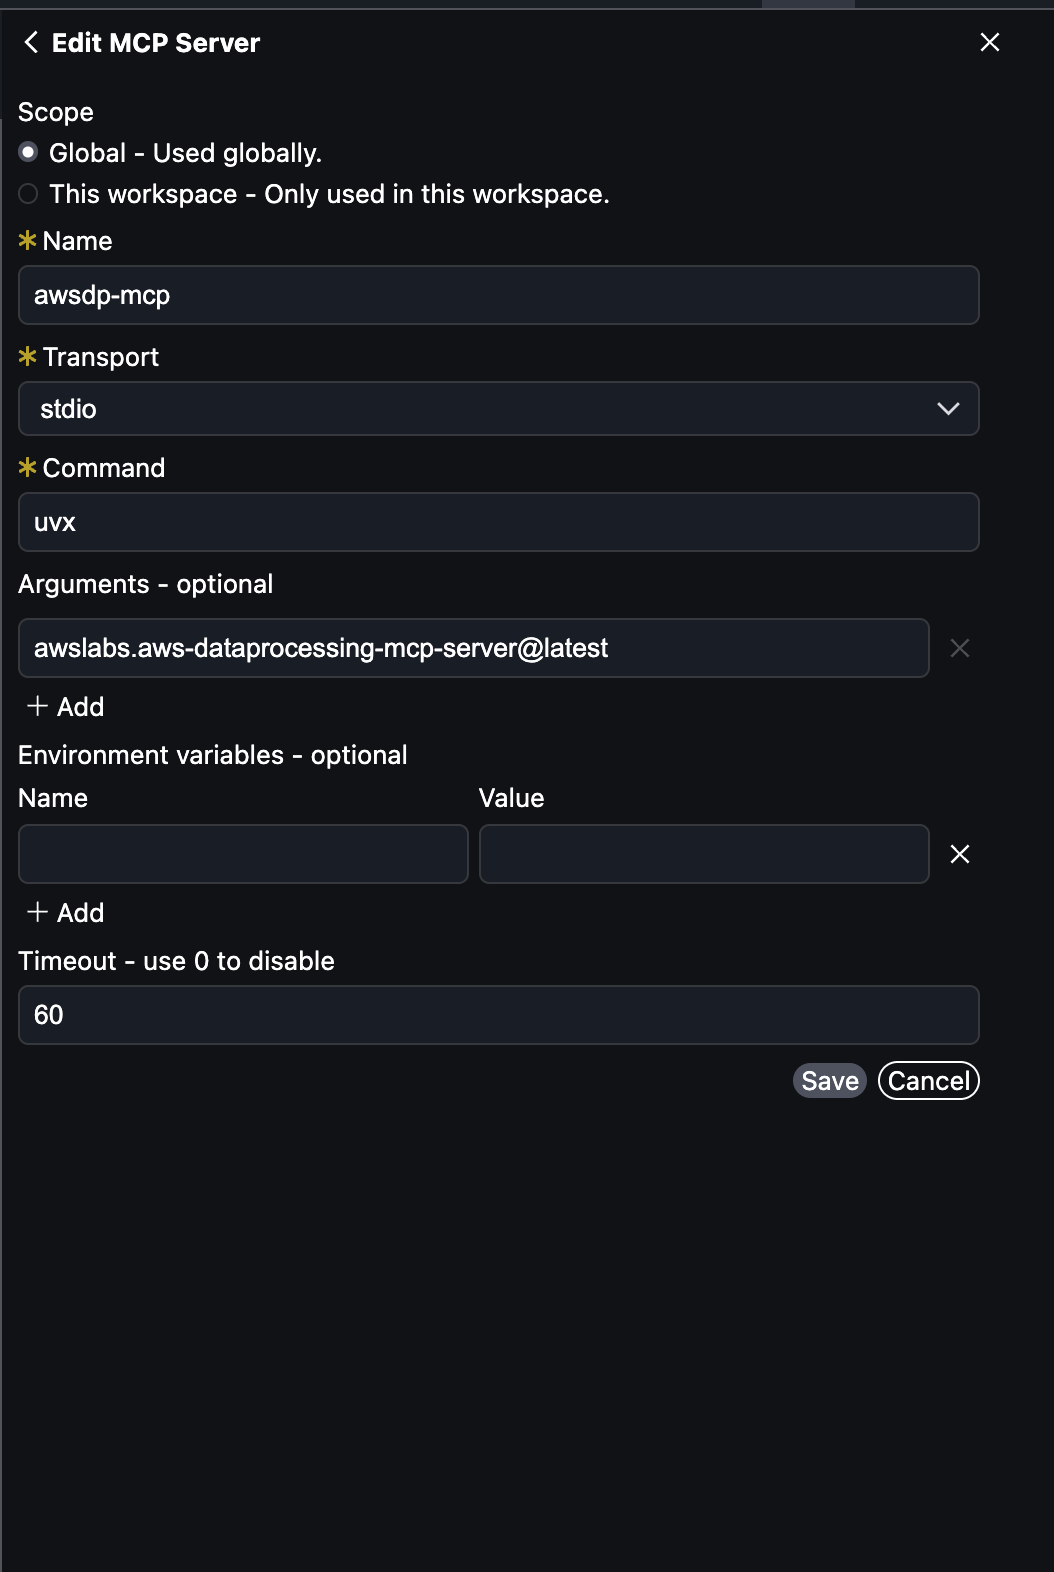
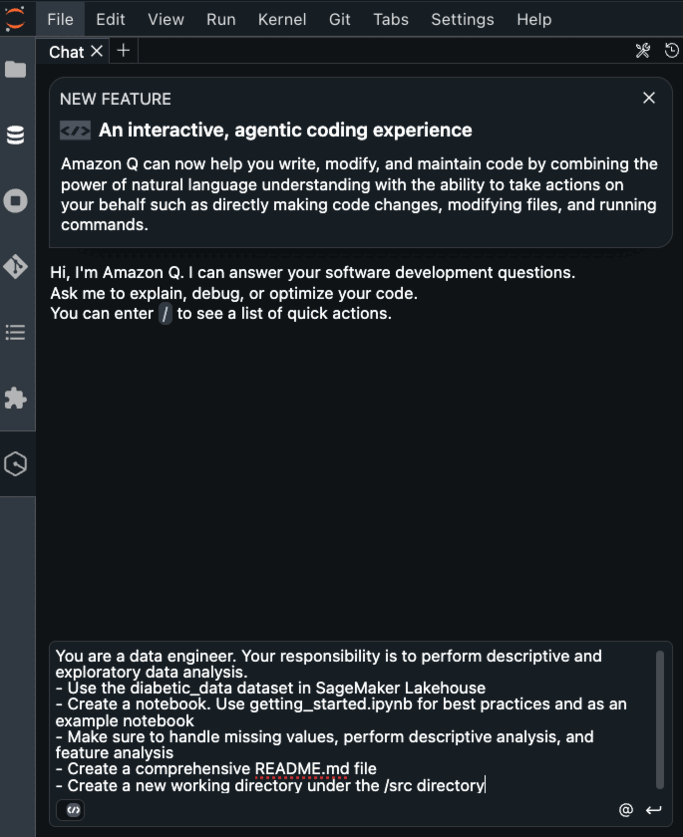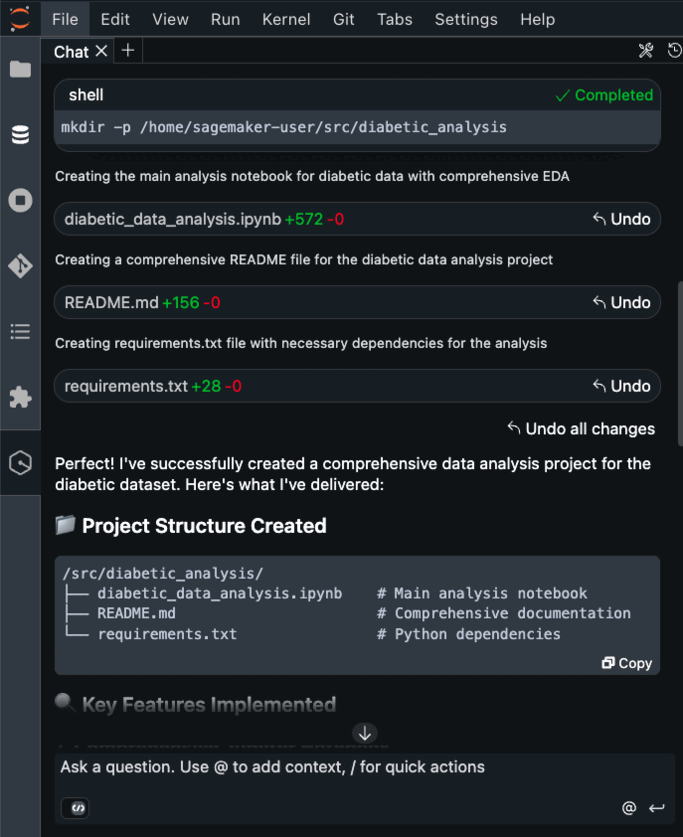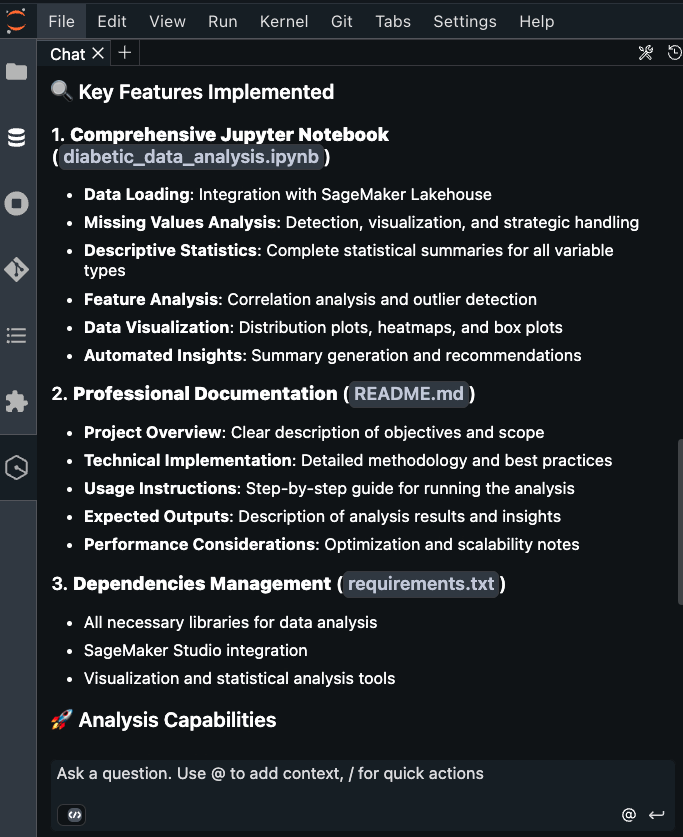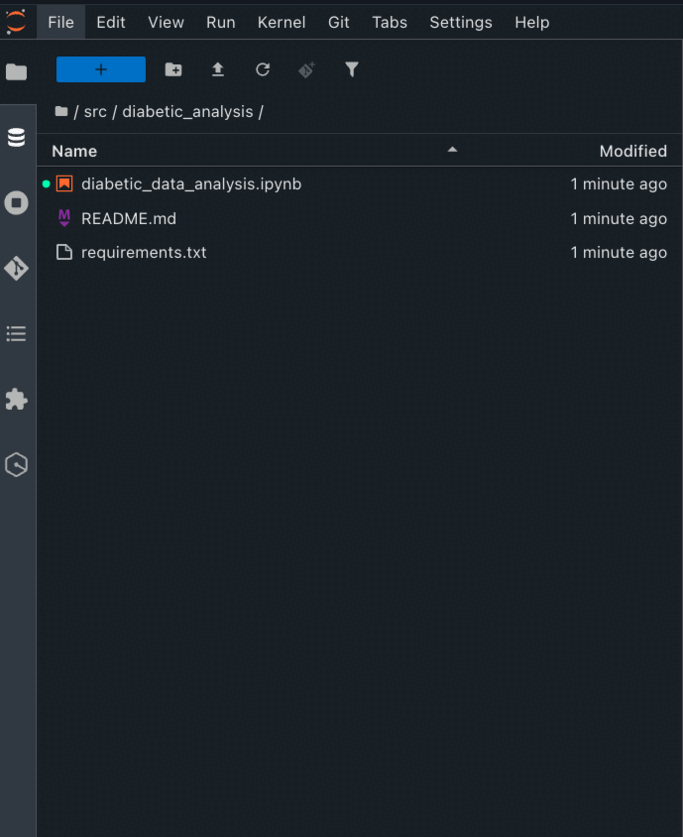
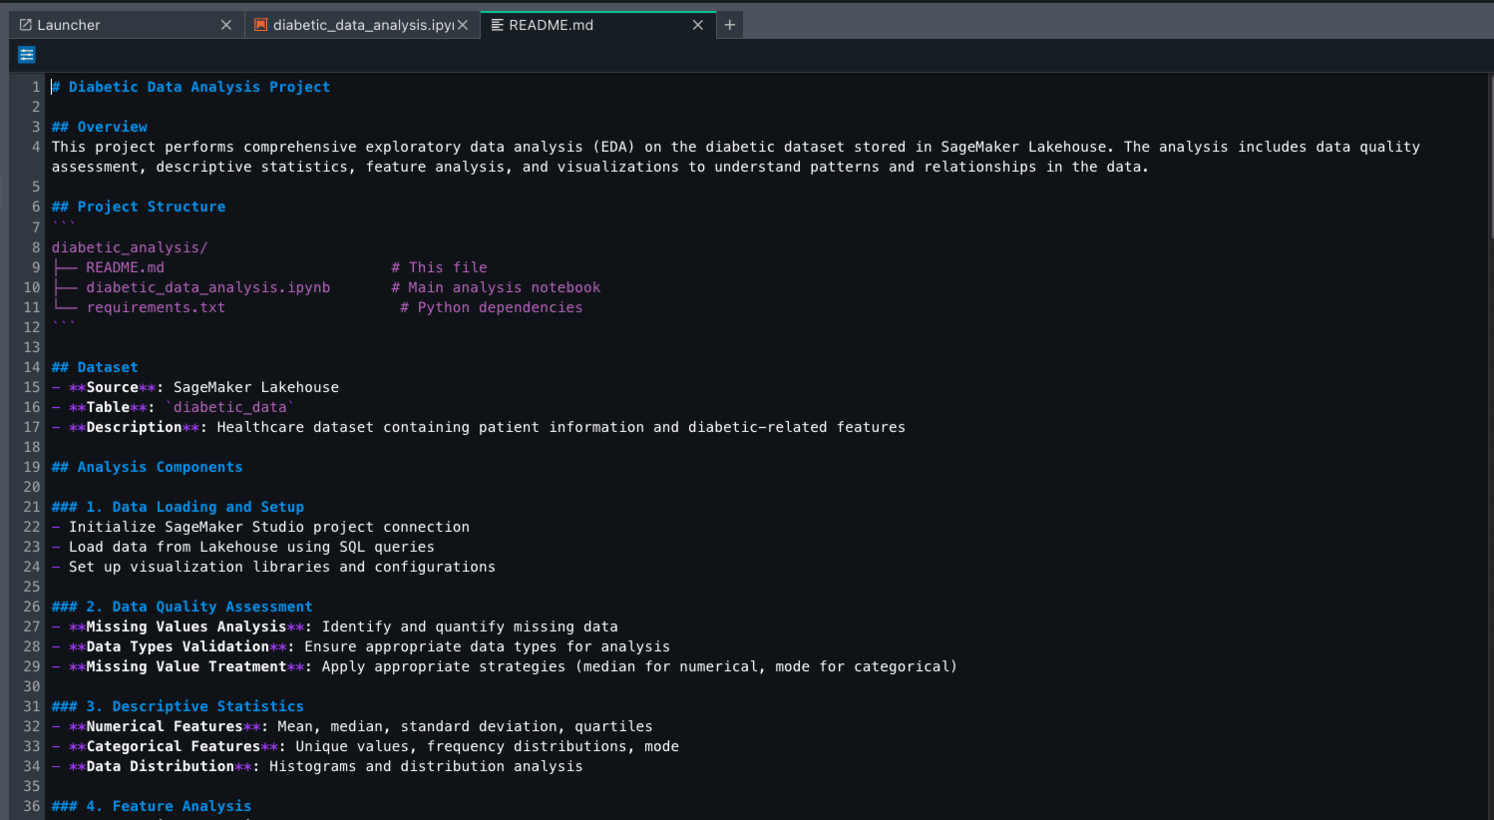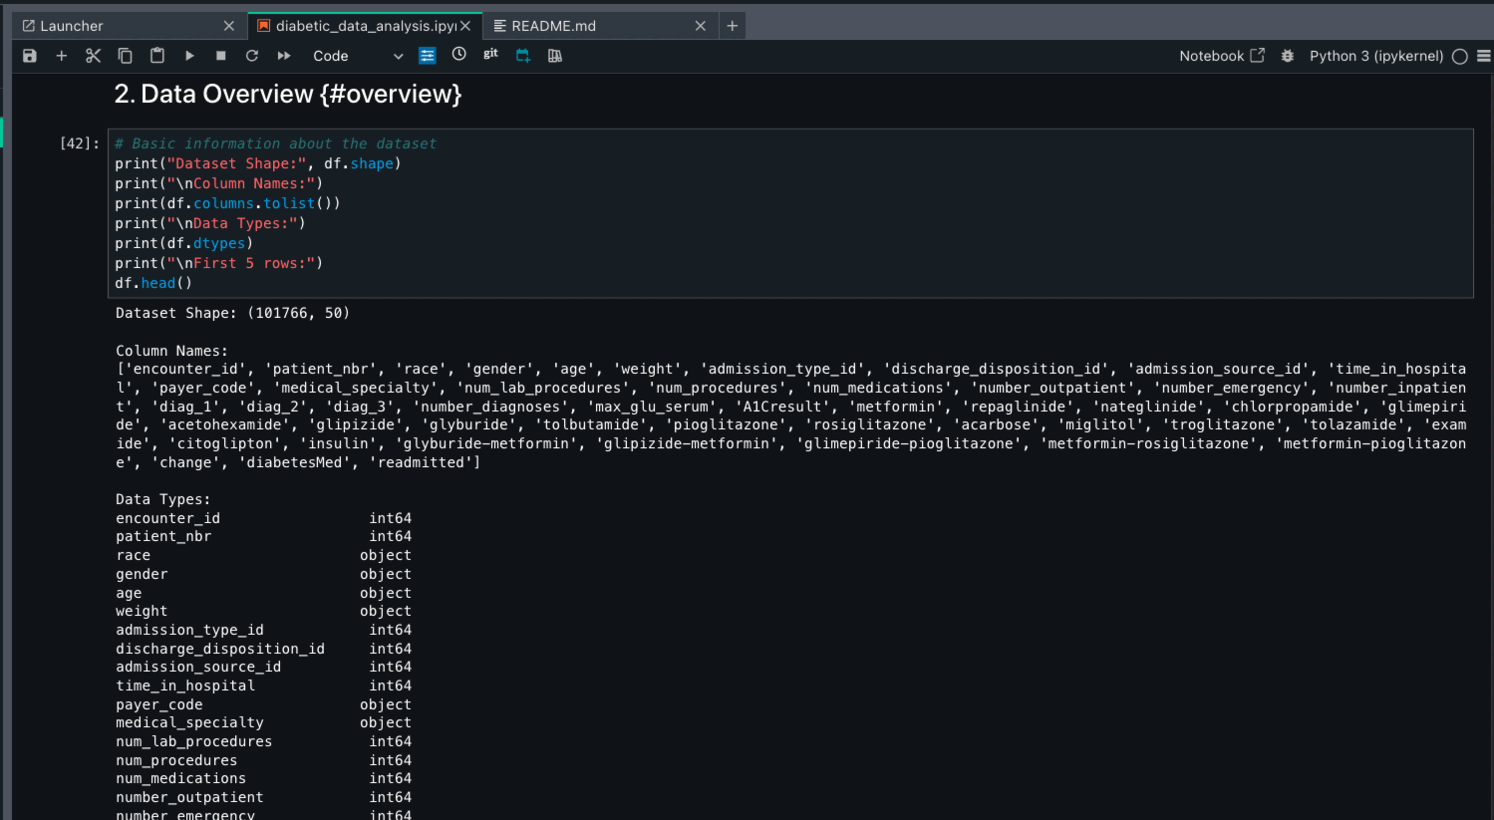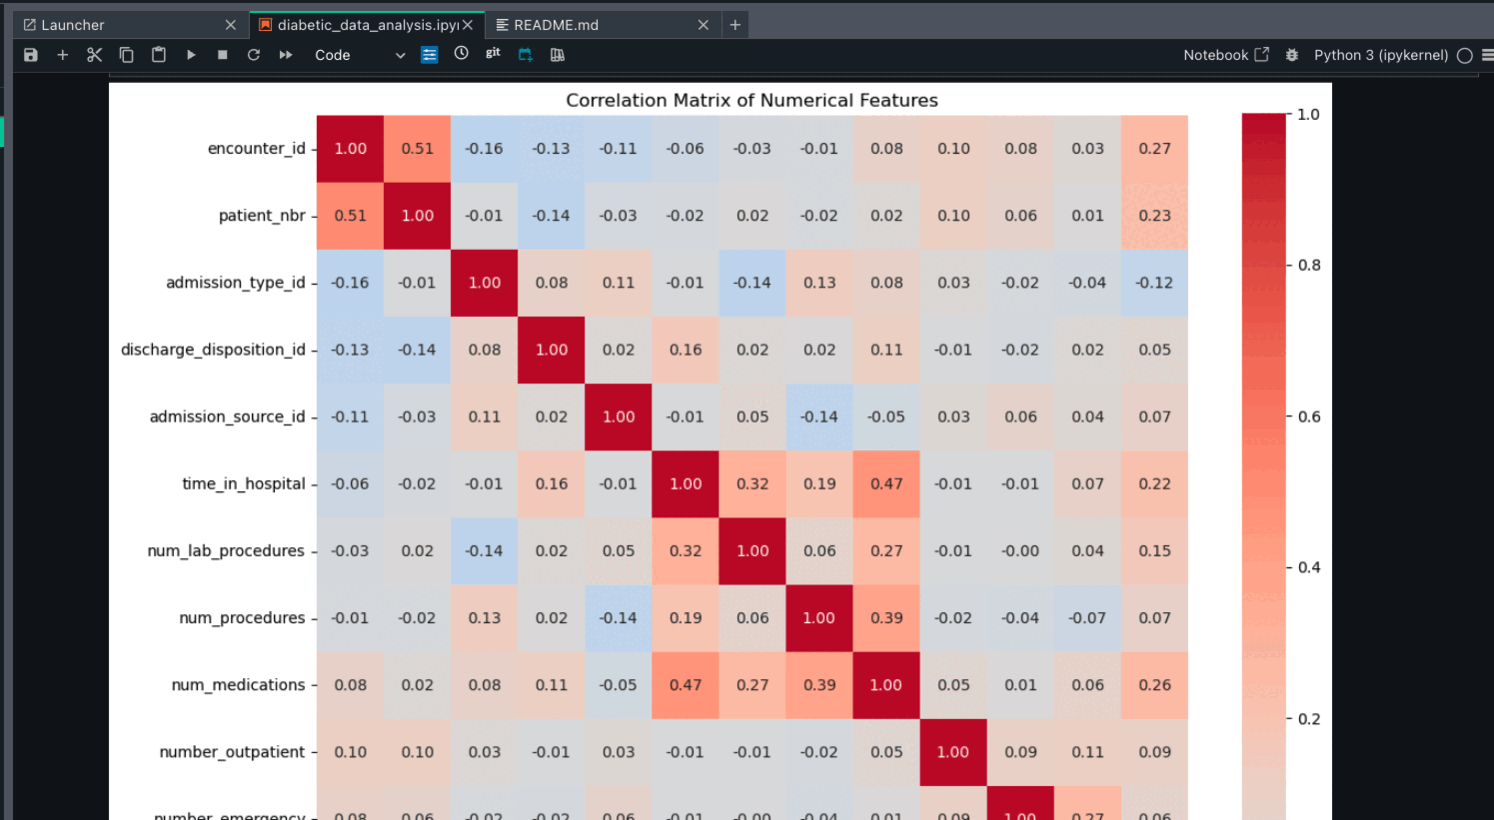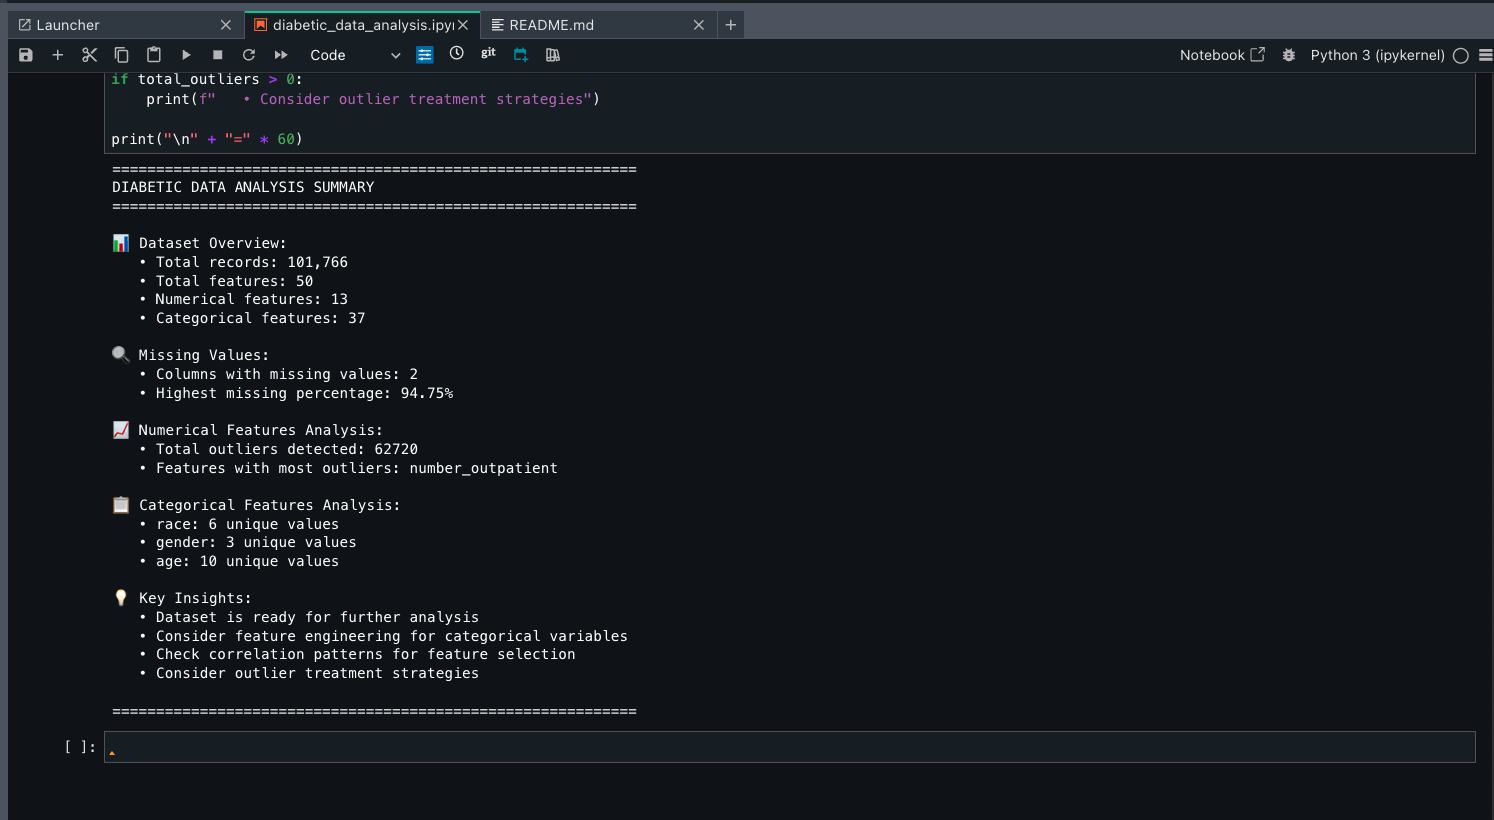
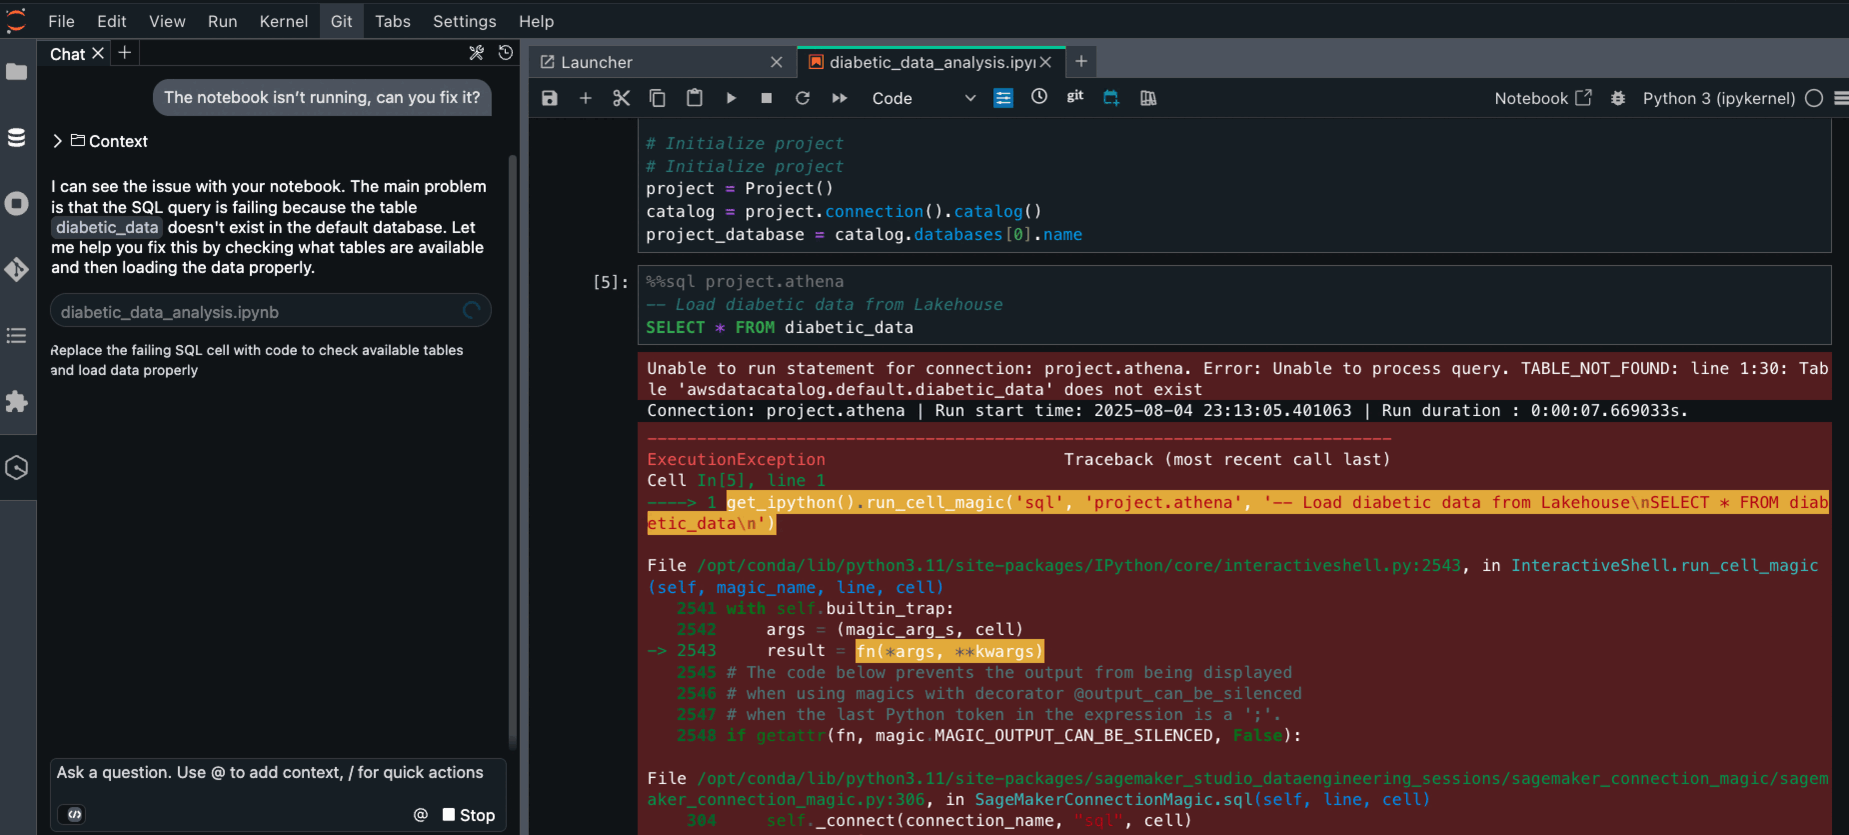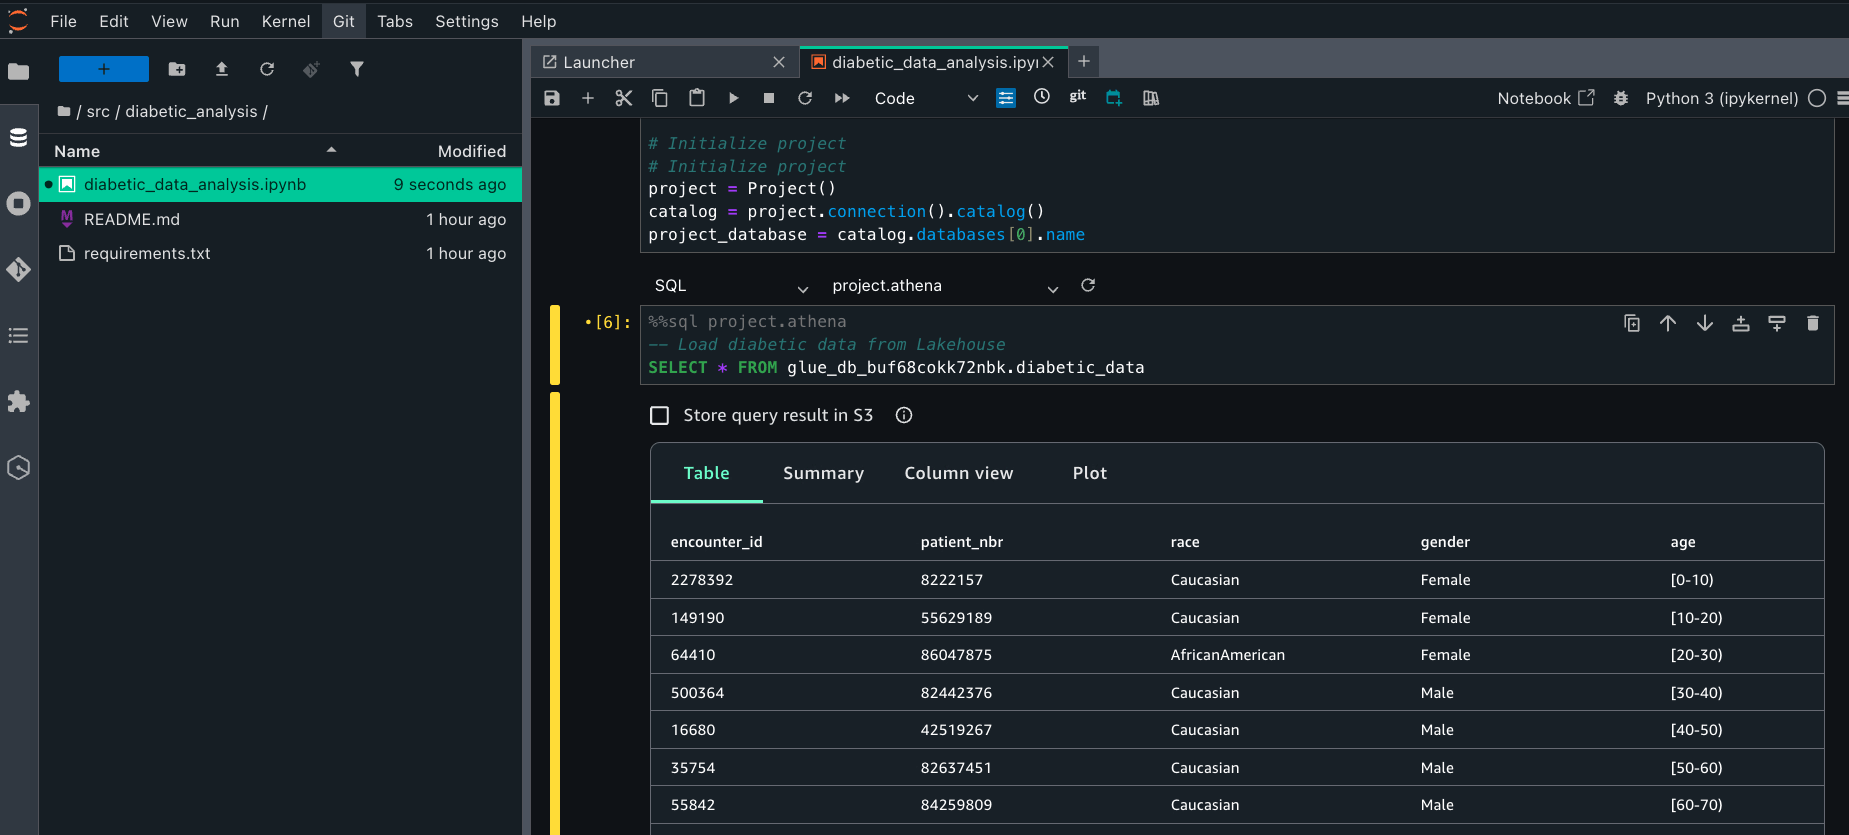
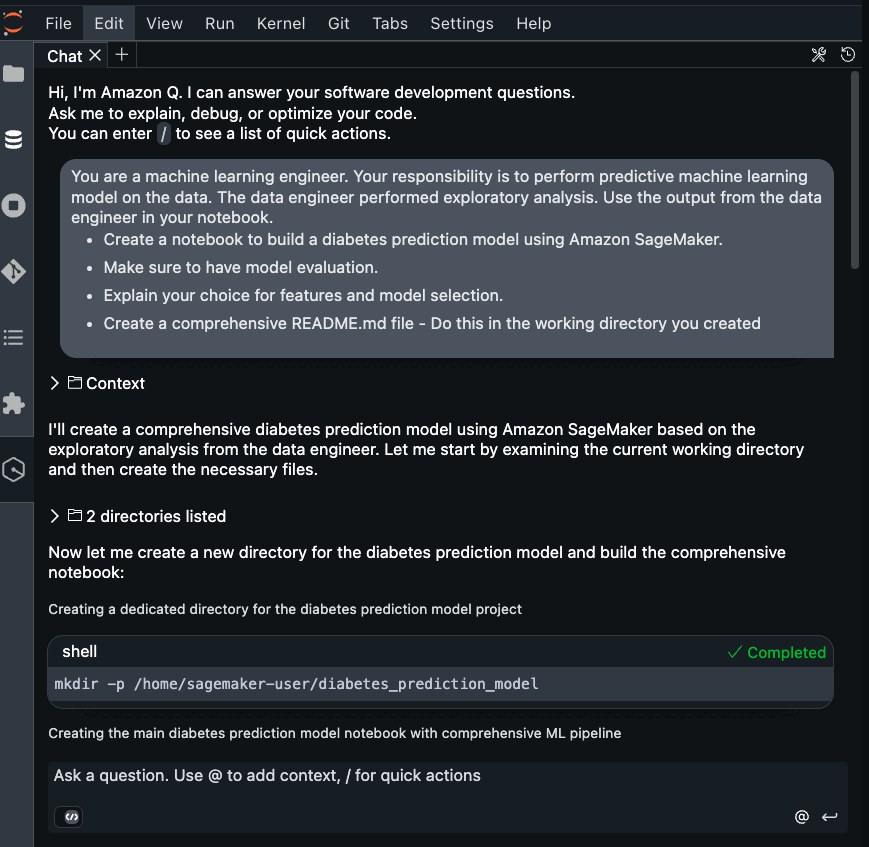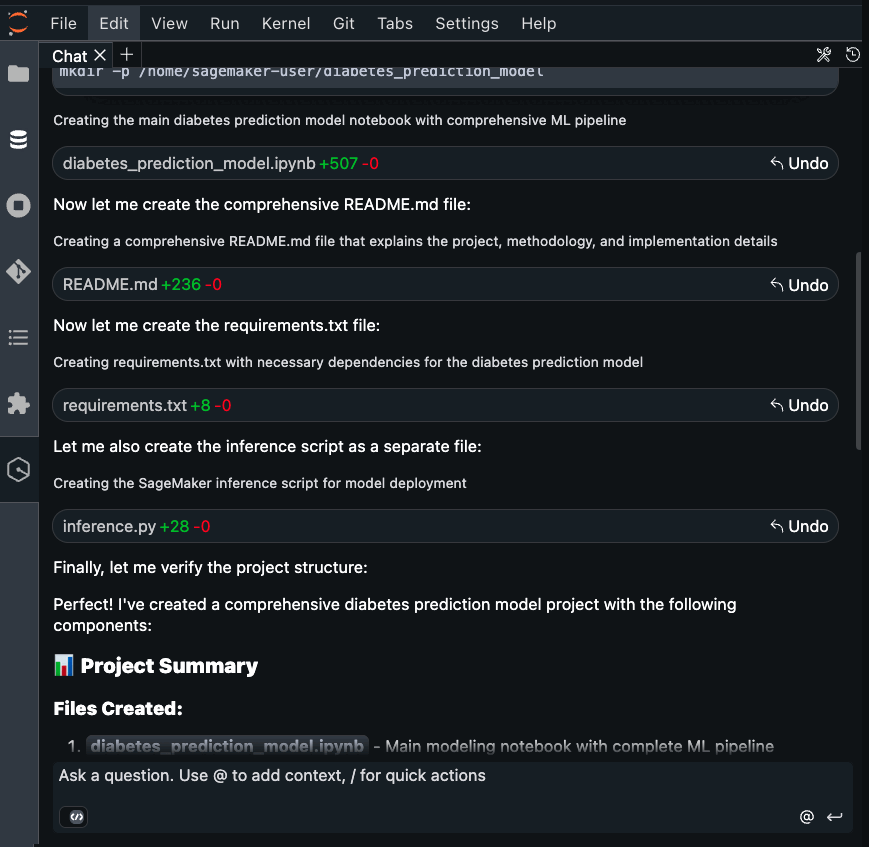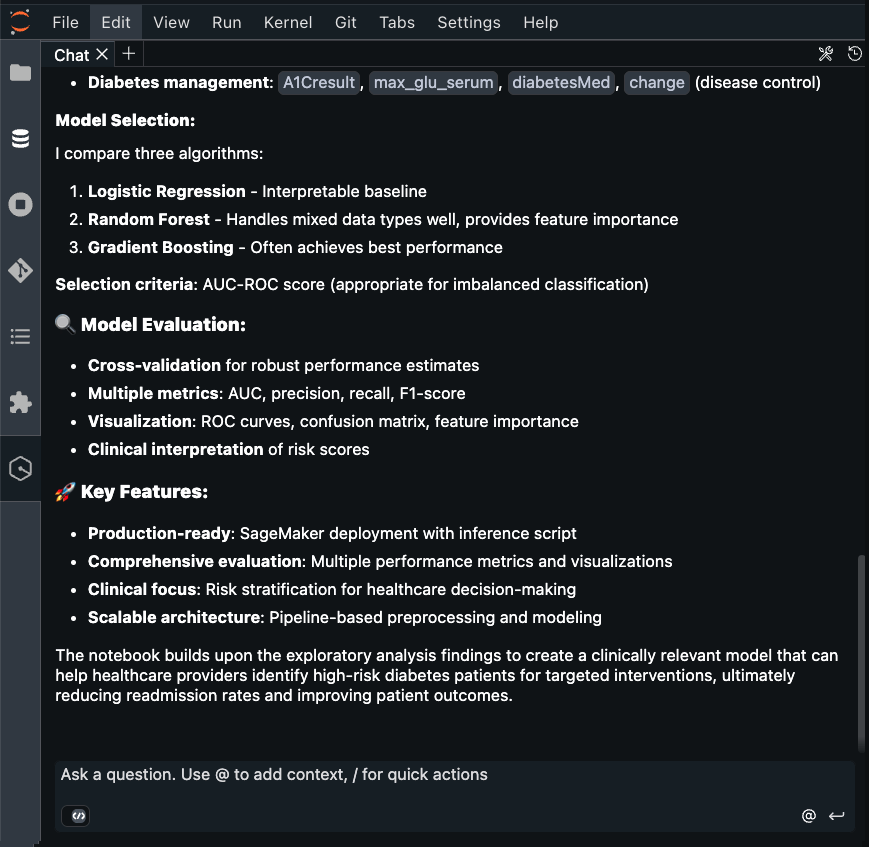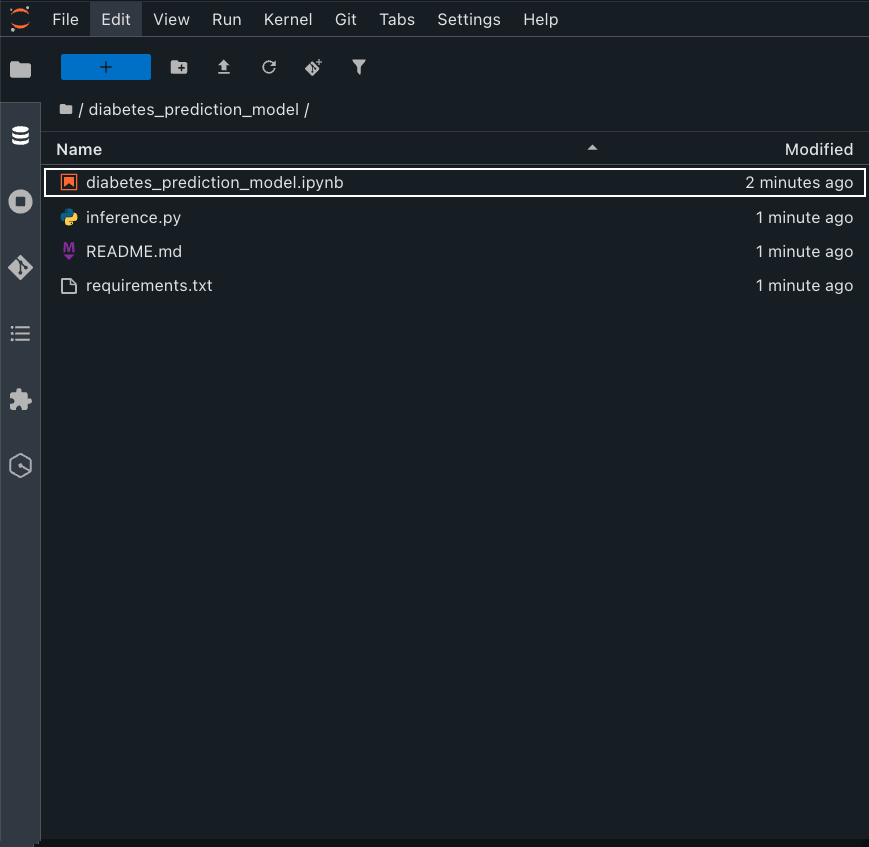
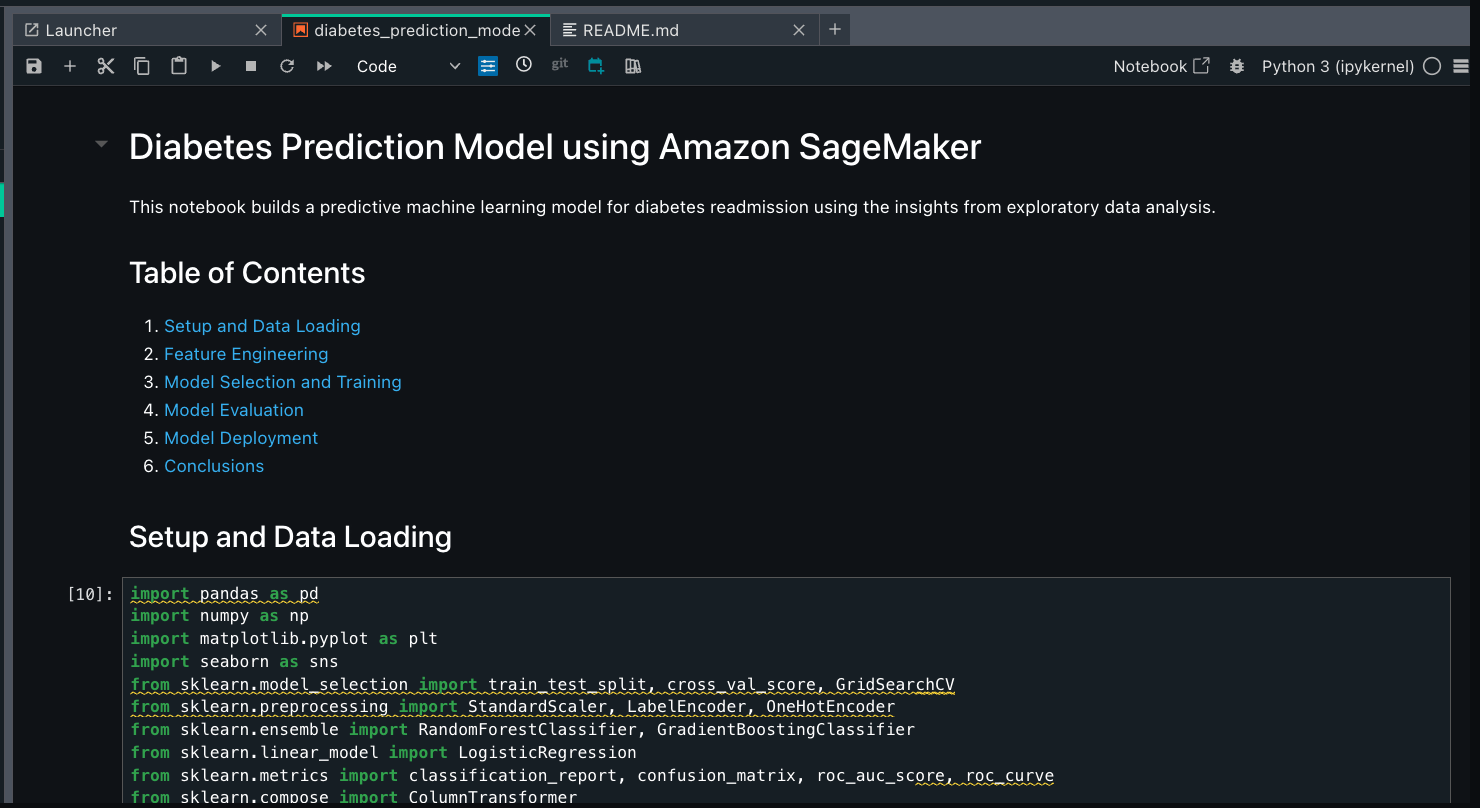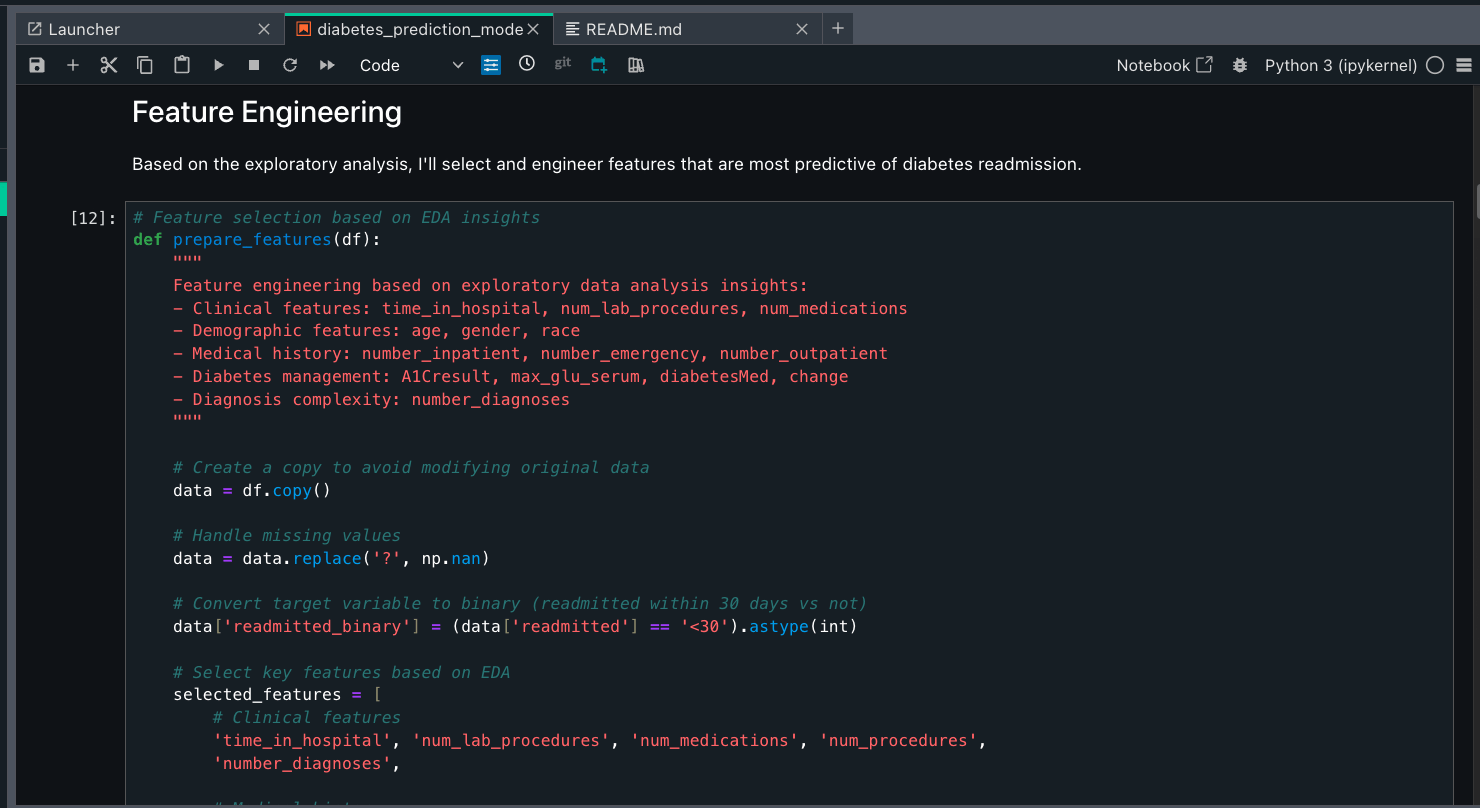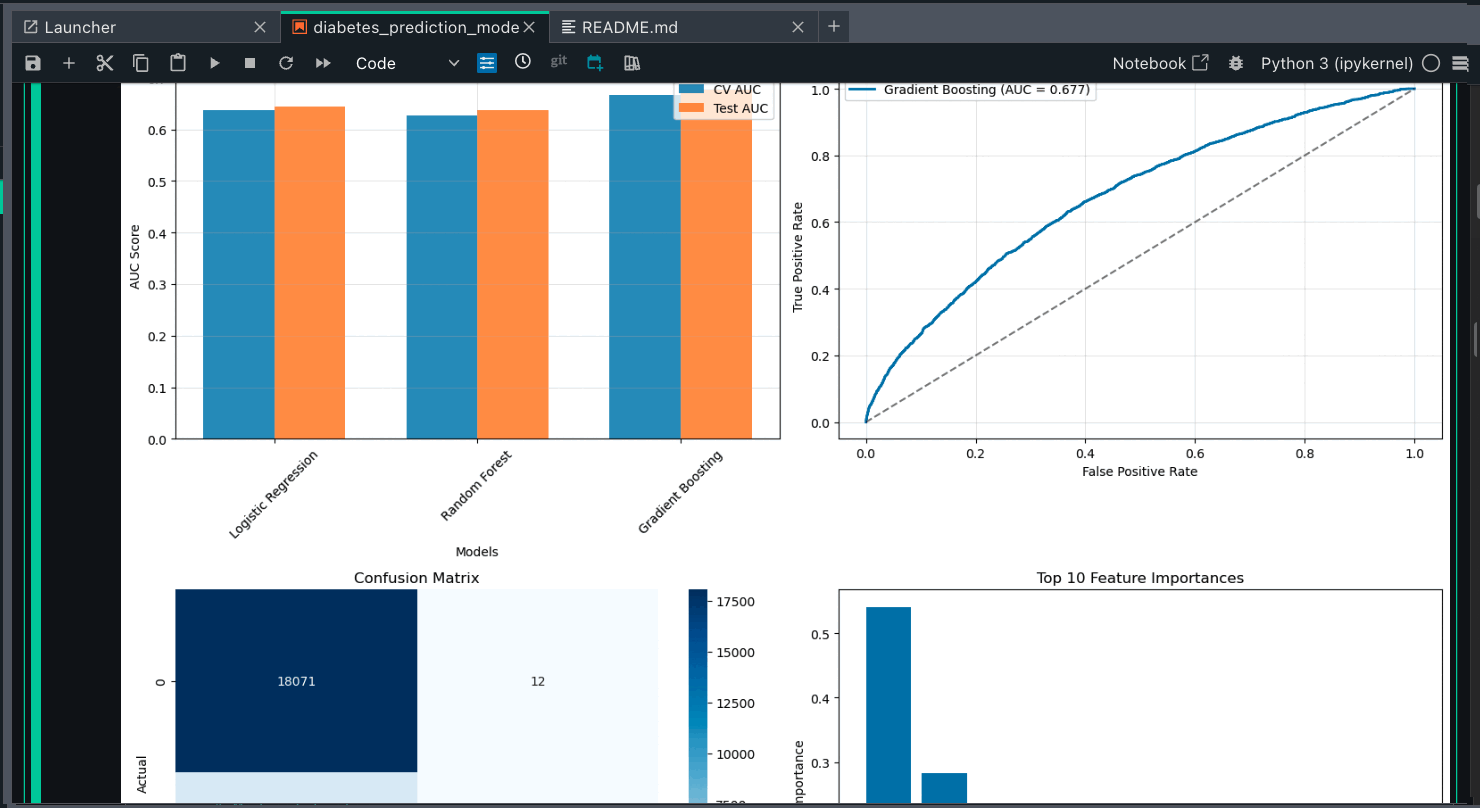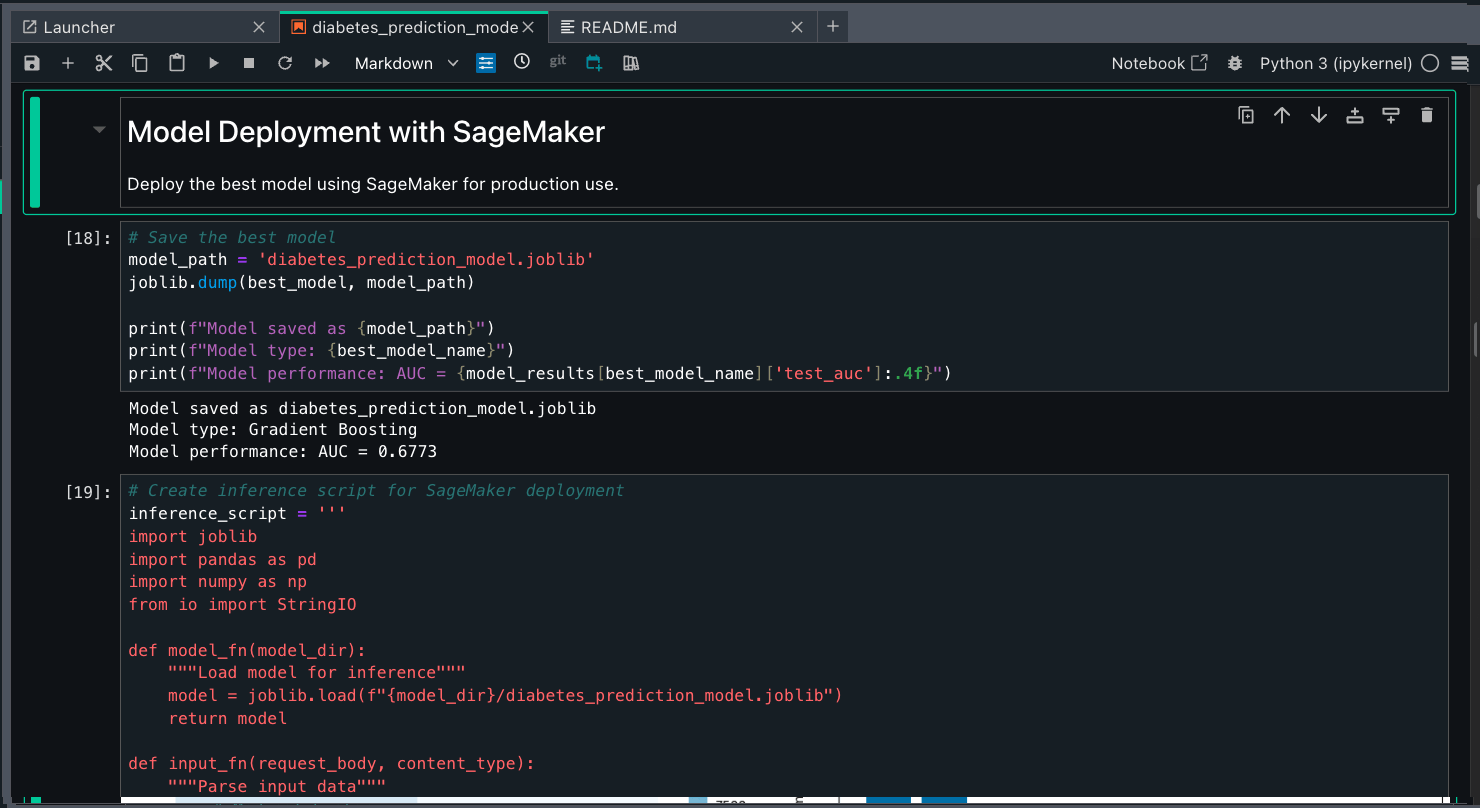
 Lauren Mullennex is a Senior GenAI/ML Specialist Solutions Architect at AWS. She has over a decade of experience in ML, DevOps, and infrastructure. She is a published author of a book on computer vision. Outside of work, you can find her traveling and hiking with her two dogs.
 Siddharth Gupta is heading Generative AI within SageMaker’s Unified Experiences. His focus is on driving agentic experiences, where AI systems act autonomously on behalf of users to accomplish complex tasks. Previously, he led edge machine learning solutions at AWS. This cutting-edge work aims to revolutionize how developers and data scientists interact with AI, creating more intuitive data integrations and powerful tools for building and deploying machine learning models. An alumnus of the University of Illinois at Urbana-Champaign, he brings extensive experience from his roles at Yahoo, Glassdoor, and Twitch. You can reach out to him on LinkedIn.
 Ishneet Kaur is a Software Development Manager on the Amazon SageMaker Unified Studio team. She leads the engineering team to design and build GenAI capabilities in SageMaker Unified Studio
 Mohan Gandhi is a Senior Software Engineer at AWS. He has been with AWS for the last 10 years and has worked on various AWS services like Amazon EMR, Amazon EFA, and Amazon RDS. Currently, he is focused on improving the SageMaker inference experience. In his spare time, he enjoys hiking and marathons.
 Mukul Prasad is a Senior Applied Science Manager in the AWS Agentic AI organization. He leads the Data Processing Agents Science team developing DevOps agents to simplify and optimize the customer journey in using AWS Big Data processing services including Amazon EMR, AWS Glue, and Amazon SageMaker Unified Studio. Outside of work, Mukul enjoys food, travel, photography, and Cricket.
 Murali Narayanaswamy is a Principal Machine Learning Scientist in the Agentic AI organization in AWS working on products including Amazon Bedrock, Amazon SageMaker Unified Studio, Amazon Redshift and Amazon RDS. His research interests lie at the intersection of AI, optimization, learning and inference particularly using them to understand, model and combat noise and uncertainty in real world applications and Reinforcement Learning in practice and at scale. Broadly, he works on using ideas from online algorithms, optimization under uncertainty, control theory, game theory, artificial intelligence, graphical models and estimation theory to solve important problems at Amazon scale.
 Necibe Ahat is a Senior AI/ML Specialist Solutions Architect at AWS, working with Healthcare and Life Sciences customers. Necibe helps customers to advance their generative AI and machine learning journey. She has a background in computer science with 15 years of industry experience helping customers ideate, design, build and deploy solutions at scale. She is a passionate inclusion and diversity advocate.
 Vipin Mohan is a Principal Product Manager at Amazon Web Services, where he leads generative AI product strategy. He specializes in building AI/ML products, container platforms, and search technologies that serve thousands of customers. Outside of work, he mentors aspiring product managers, enjoys reading about financial investing and entrepreneurship, and loves exploring the world through the eyes of his two kids.