2024 marks Cloudflare’s 14th birthday. Birthday Week each year is packed with major announcements and the release of innovative new offerings, all focused on giving back to our customers and the broader Internet community. Birthday Week has become a proud tradition at Cloudflare and our culture, to not just stay true to our mission, but to always stay close to our customers. We begin planning for this week of celebration earlier in the year and invite everyone at Cloudflare to participate.
Months before Birthday Week, we invited teams to submit ideas for what to announce. We were flooded with submissions, from proposals for implementing new standards to creating new products for developers. Our biggest challenge is finding space for it all in just one week — there is still so much to build. Good thing we have a birthday to celebrate each year, but we might need an extra day in Birthday Week next year!
In case you missed it, here’s everything we announced during 2024’s Birthday Week:
Customers using Cloudflare to manage DNS can create a whole batch of records, enable proxying on many records, update many records to point to a new target at the same time, or even delete all of their records.
Taking the next step in advancing security with Ephemeral IDs, a new feature that generates a unique short-lived ID, without relying on any network-level information.
Speed Brain, our latest leap forward in speed, uses the Speculation Rules API to prefetch content for users’ likely next navigations — downloading web pages before they navigate to them and making pages load 45% faster.
Instant Purge invalidates cached content in under 150ms, offering the industry’s fastest cache purge with global latency for purges by tags, hostnames, and prefixes.
Next generation servers focused on exceptional performance and security, enhanced support for AI/ML workloads, and significant strides in power efficiency.
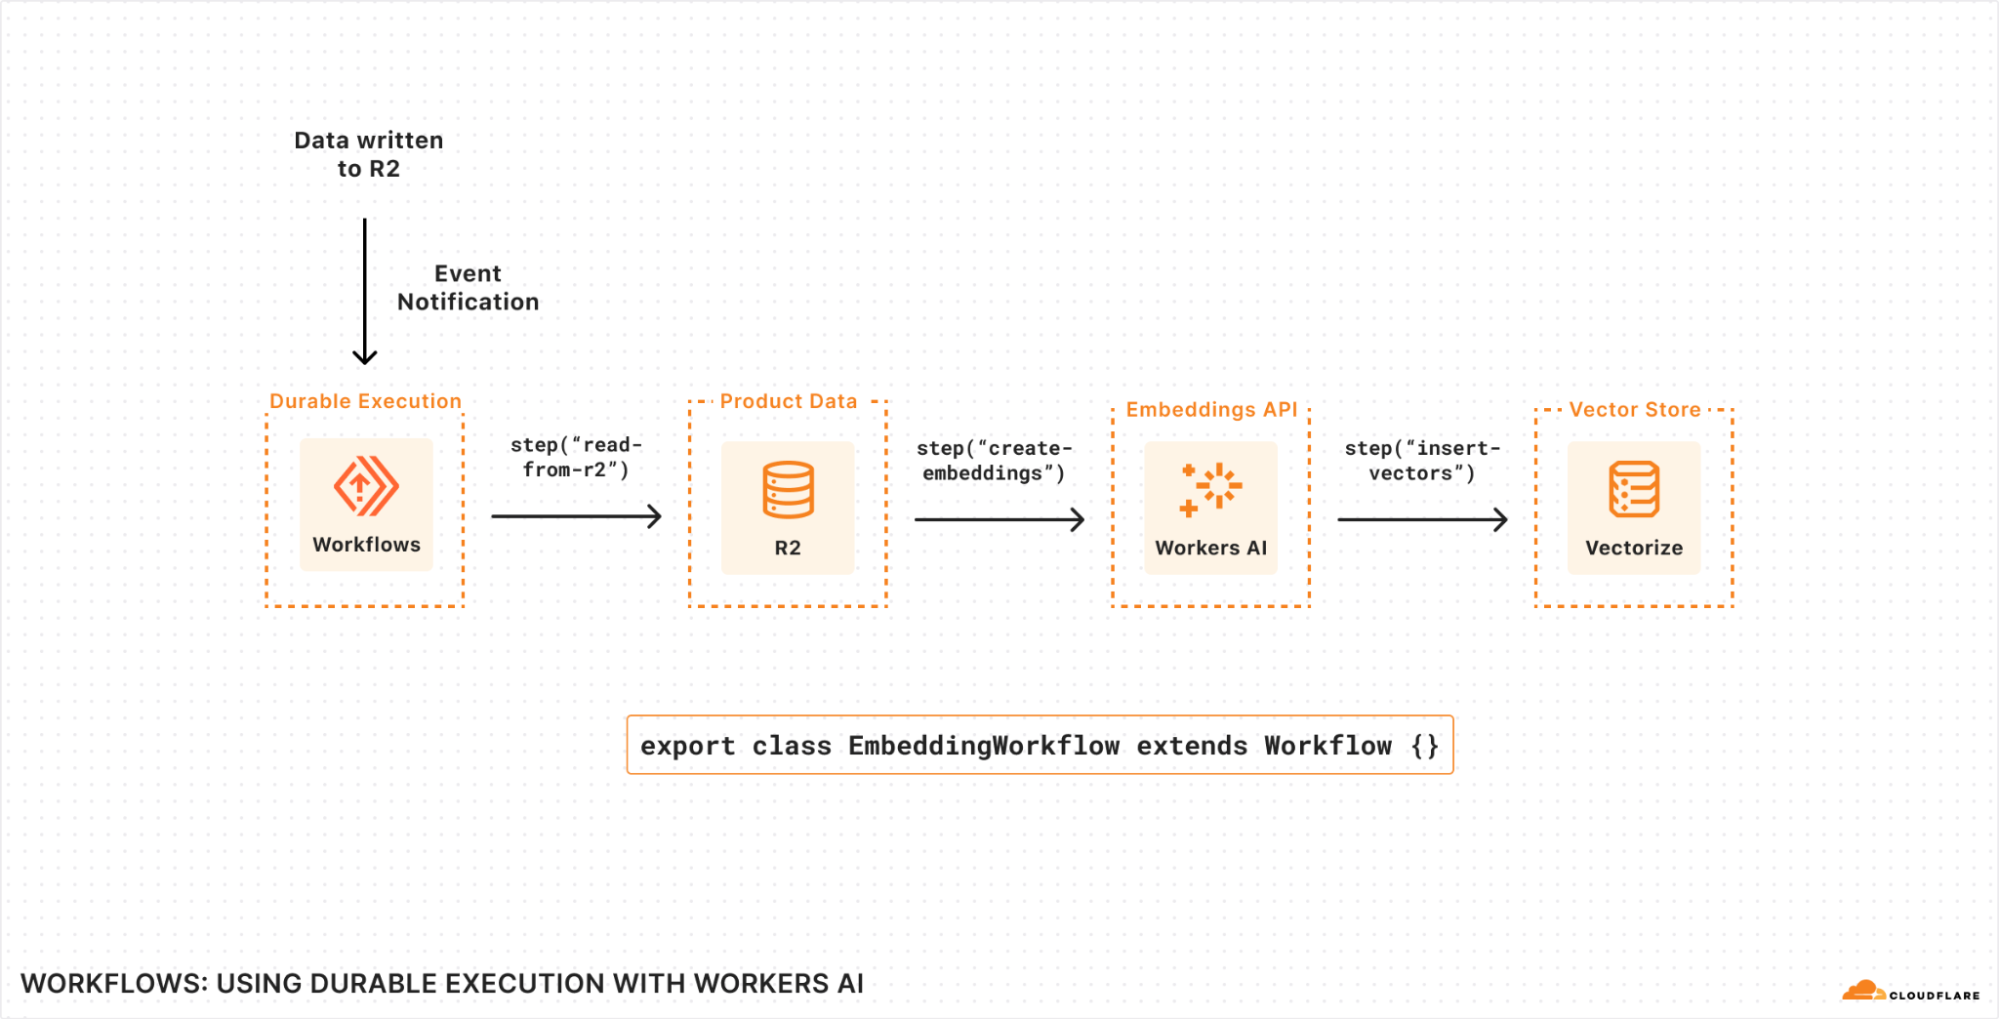
More powerful GPUs, expanded model support, enhanced logging and evaluations in AI Gateway, and Vectorize GA with larger index sizes and faster queries.
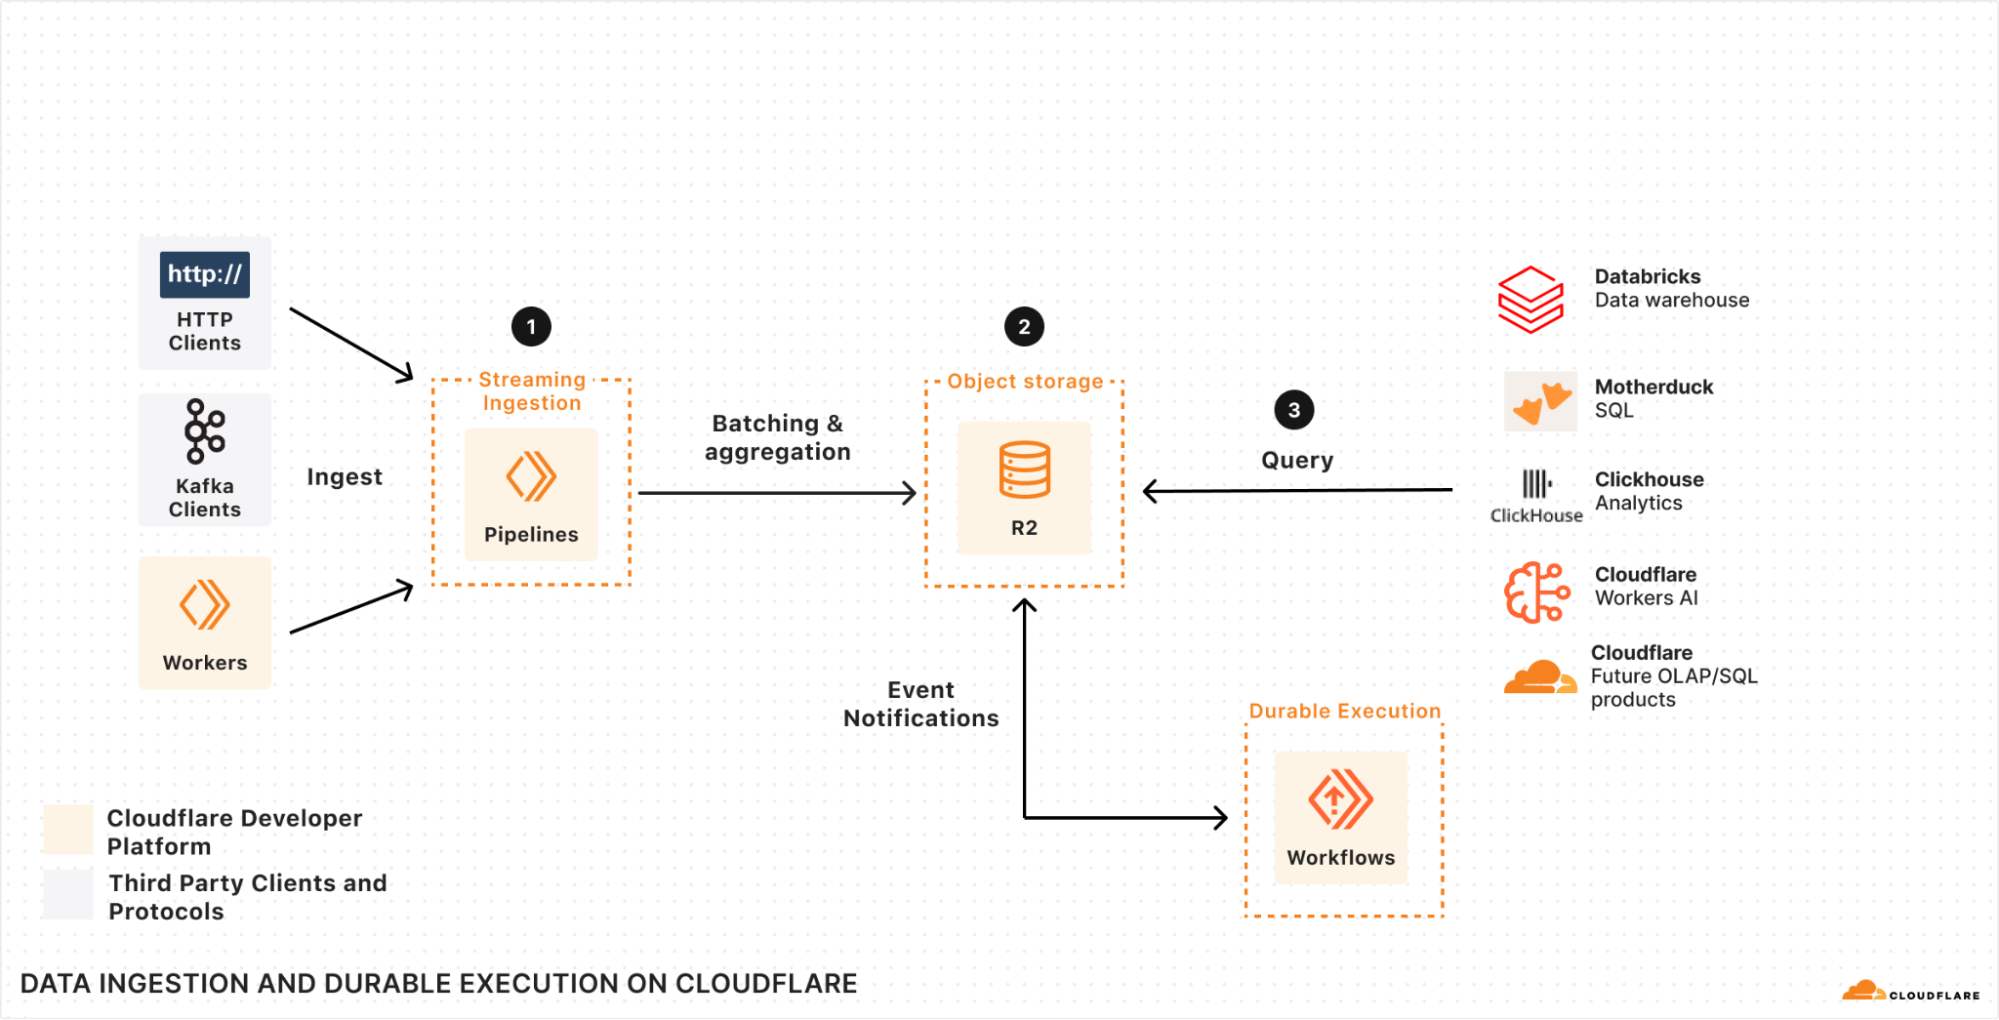
Persistent and queryable Workers logs, Node.js compatibility GA, improved Next.js support via OpenNext, built-in CI/CD for Workers, Gradual Deployments, Queues, and R2 Event Notifications GA, and more — making building on Cloudflare easier, faster, and more affordable.
Using new optimization techniques such as KV cache compression and speculative decoding, we’ve made large language model (LLM) inference lightning-fast on the Cloudflare Workers AI platform.
We’ve been working on something new — a platform for running containers across Cloudflare’s network. We already use it in production, for AI inference and more.
Extending our AI Assistant capabilities to help you build new WAF rules, added new AI bot and crawler traffic insights to Radar, and new AI bot blocking capabilities.
Our free plan is here to stay, and we reaffirm that commitment this week with 15 releases that make the Free plan even better.
One more thing…
Cloudflare serves millions of customers and their millions of domains across nearly every country on Earth. However, as a global company, the payment landscape can be complex — especially in regions outside of North America. While credit cards are very popular for online purchases in the US, the global picture is quite different. 60% of consumers across EMEA, APAC and LATAM choose alternative payment methods. For instance, European consumers often opt for SEPA Direct Debit, a bank transfer mechanism, while Chinese consumers frequently use Alipay, a digital wallet.
At Cloudflare, we saw this as an opportunity to meet customers where they are. Today, we’re thrilled to announce that we are expanding our payment system and launching a closed beta for a new payment method called Stripe Link. The checkout experience will be faster and more seamless, allowing our self-serve customers to pay using saved bank accounts or cards with Link. Customers who have saved their payment details at any business using Link can quickly check out without having to reenter their payment information.
These are the first steps in our efforts to expand our payment system to support global payment methods used by customers around the world.We’ll be rolling out new payment methods gradually, ensuring a smooth integration and gathering feedback from our customers every step of the way.
Until next year
That’s all for Birthday Week 2024. However, the innovation never stops at Cloudflare. Continue to follow the Cloudflare Blog all year long as we launch more products and features that help build a better Internet.
Today we’re announcing the Dev Starter Pack, an alliance of innovative tools for developers to get started with discounts and free services. We’re also excited to share an update on our Workers Launchpad Program.
Creating from the ground up often means spending countless hours piecing together the right development stack, navigating different pricing models, and managing growing costs — all of which can take your focus away from what truly matters: building your product and growing your business.
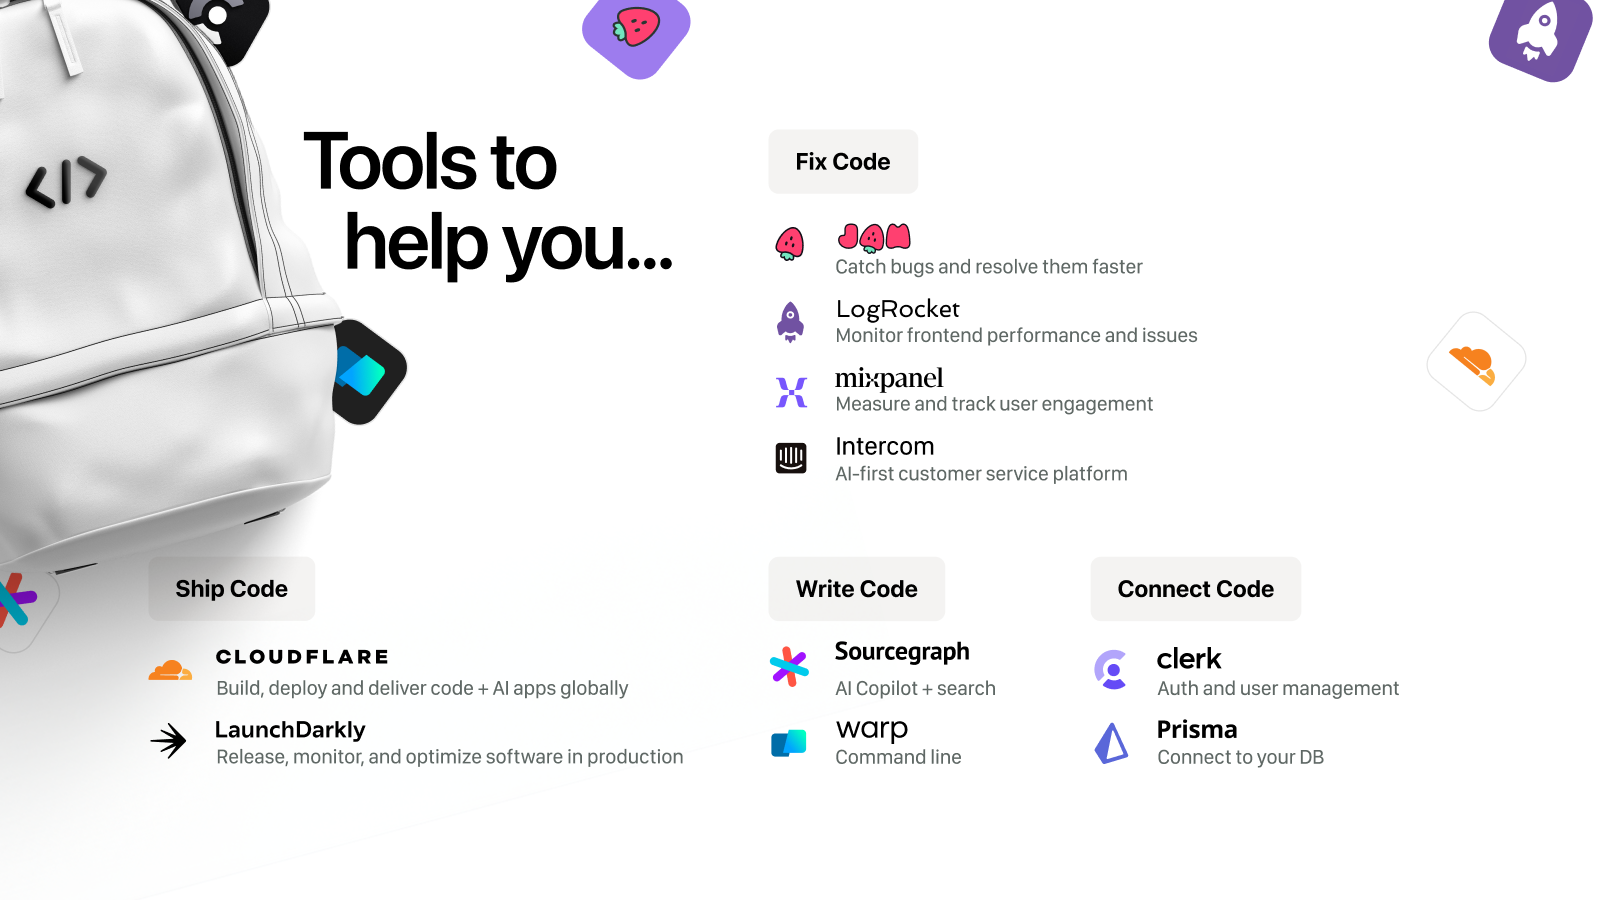
Introducing Dev Starter Pack: the tools you need to start building your startup
Hey! Dani Grant here, one of the first PMs at Cloudflare and co-founder of Jam.dev. Ten years ago (during 2014’s Birthday Week), Cloudflare launched Universal SSL, making SSL free on the Internet for the first time, and in one night doubling the size of the encrypted web.
I was a college student back then, and I immediately became enraptured by Cloudflare’s mission: helping build a better Internet. As part of this mission, Cloudflare has developed powerful tools typically accessible only to Internet giants, oftentimes offering them for free to developers and individuals alike. Heck yeah! I joined Cloudflare in January 2015, and 5 years after that, co-founded a developer tool company called Jam, inspired by the impact that I saw building tools for developers could have while at Cloudflare.
It’s now 10 years later, and a lot has changed –– “software ate the world” and it’s now powering all aspects of our lives, from health to finances to how we work. It’s more important than ever to empower every developer with the best tools available, because the faster we build software, the sooner people’s experiences improve.
Today we’re thrilled to announce the Dev Starter Pack, an alliance of like-minded dev tool companies giving away their services for free, or heavily discounting them for developers who want to start companies and build the future.
Not only does this stack include all the tools you need to build a startup, it also includes all the tools you need to build AI-powered features. We believe that the next wave of startups will be AI-native, as AI becomes as ubiquitous as the electricity that powers the servers.
We haven’t even scratched the surface of what’s possible with AI, and we hope this launch gets developers closer to solving the challenges of building non-deterministic software.
If you’re a software engineer, and you want to build a project or a company and need an off the shelf stack of dev tools to get started, go to devstarterpack.io to start using all of these tools.
Each provider is offering developers a heavily discounted or even free plan to get started building. You can redeem these services by either using the special code “devstarterpack” or selecting “Dev Starter Pack” while applying to relevant programs.
We welcome more tools to join the alliance — this is just the beginning. If you are building a developer tool and would like to include your product in the Dev Starter Pack, let us know here, so we can include you.
What will you build?
We are very excited to see what you will build. Please share with us in Cloudflare’s Discord and community forum, so we can support you however it makes sense.
Software developers are changing the world, and we believe in providing support to help you make an even greater impact. If you’re looking for additional funding or support, check out Cloudflare’s Launchpad for developers turned founders building startups.
Introducing Workers Launchpad Cohort #4
Melissa and Chris from the Cloudflare for Startups team here. Our team is blown away by what customers are demonstrating on the Developer Platform. Just a few weeks ago, our Workers Launchpad Cohort #3 wrapped up. On Demo Day, customers demoed their applications built on Cloudflare, spanning AI, dev tools, IaaS, observability, SaaS, media, and beyond. We’re incredibly proud of Cohort #3 participants, and we look forward to their continued success with Cloudflare.
Following Demo Day of Workers Launchpad Cohort #3, we’ve been excited to receive a surge of new applications from startups around the world. These startups are pushing the boundaries of innovation, particularly in areas like observability, PaaS, AI, automation, e-commerce, and other industries. Many startups that applied this go-around demonstrated that they’ve built some great applications on Cloudflare, and today, we’re excited to announce the accepted participants for our upcoming Workers Launchpad Cohort #4.
Let’s take a look at what Cohort #4 participants are building in their own words:
The Cloudflare team is ecstatic to work with the amazing participants of Cohort #4. If you want to follow along on Cohort #4’s journey, be sure to follow @CloudflareDev on X and join our Developer Discord server.
To celebrate Builder Day 2024, we’re shipping 18 updates inspired by direct feedback from developers building on Cloudflare. Choosing a platform isn’t just about current technologies and services — it’s about betting on a partner that will evolve with your needs as your project grows and the tech landscape shifts. We’re in it for the long haul with you.
Everything in this post is available for you to use today. Keep reading to learn more, and watch the Builder Day Live Stream for demos and more.
Persistent Logs for every Worker
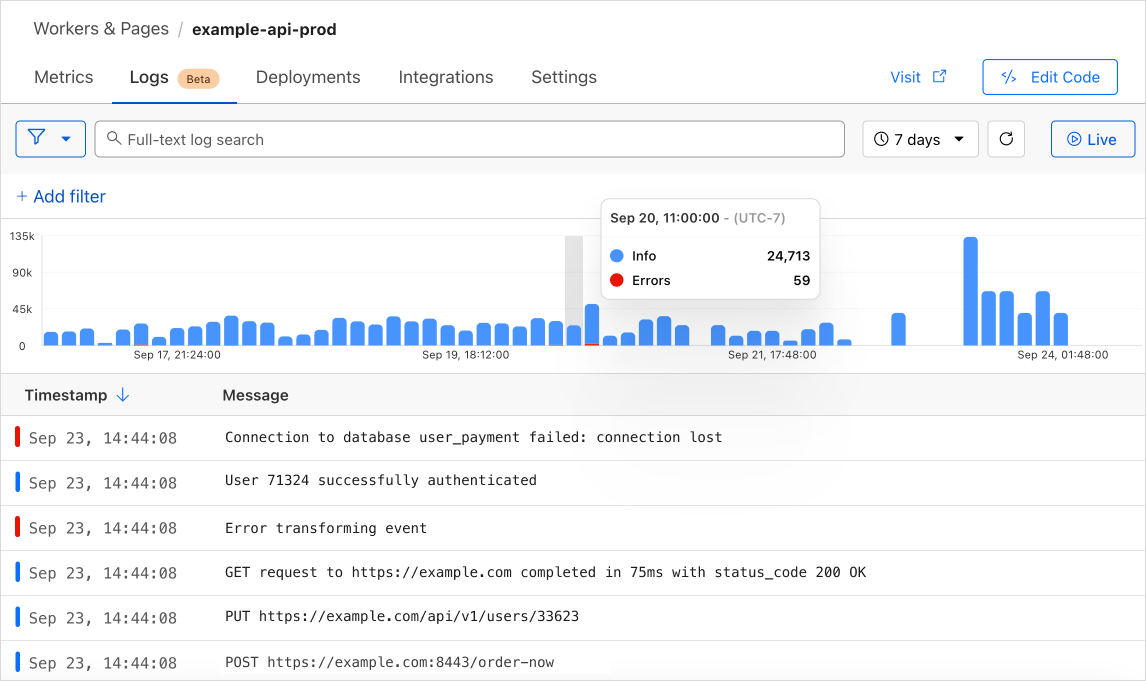
Starting today in open beta, you can automatically retain logs from your Worker, with full search, query, and filtering capabilities available directly within the Cloudflare dashboard. All newly created Workers will have this setting automatically enabled. This marks the first step in the development of our observability platform, following Cloudflare’s acquisition of Baselime.
Getting started is easy – just add two lines to your Worker’s wrangler.toml and redeploy:
[observability]
enabled = true
Workers Logs allow you to view all logs emitted from your Worker. When enabled, each console.log message, error, and exception is published as a separate event. Every Worker invocation (i.e. requests, alarms, rpc, etc.) also publishes an enriched execution log that contains invocation metadata. You can view logs in the Logs tab of your Worker in the dashboard, where you can filter on any event field, such as time, error code, message, or your own custom field.
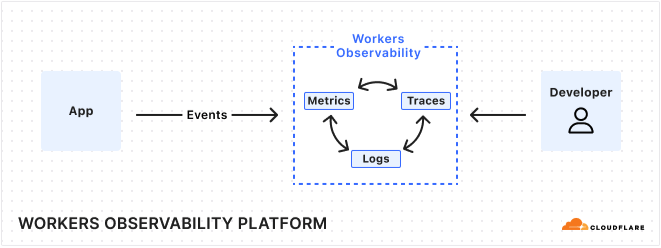
If you’ve ever had to piece together the puzzle of unusual metrics, such as a spike in errors or latency, you know how frustrating it is to connect metrics to traces and logs that often live in independent data silos. Workers Logs is the first piece of a new observability platform we are building that helps you easily correlate telemetry data, and surfaces insights to help you understand. We’ll structure your telemetry data so you have the full context to ask the right questions, and can quickly and easily analyze the behavior of your applications. This is just the beginning for observability tools for Workers. We are already working on automatically emitting distributed traces from Workers, with real time errors and wide, high dimensionality events coming soon as well.
Starting November 1, 2024, Workers Logs will cost $0.60 per million log lines written after the included volume, as shown in the table below. Querying your logs is free. This makes it easy to estimate and forecast your costs — we think you shouldn’t have to calculate the number of ‘Gigabytes Ingested’ to understand what you’ll pay.
Workers Free
Workers Paid
Included Volume
200,000 logs per day
20,000,000 logs per month
Additional Events
N/A
$0.60 per million logs
Retention
3 days
7 days
Try out Workers Logs today. You can learn more from our developer documentation, and give us feedback directly in the #workers-observability channel on Discord.
Connect to private databases from Workers
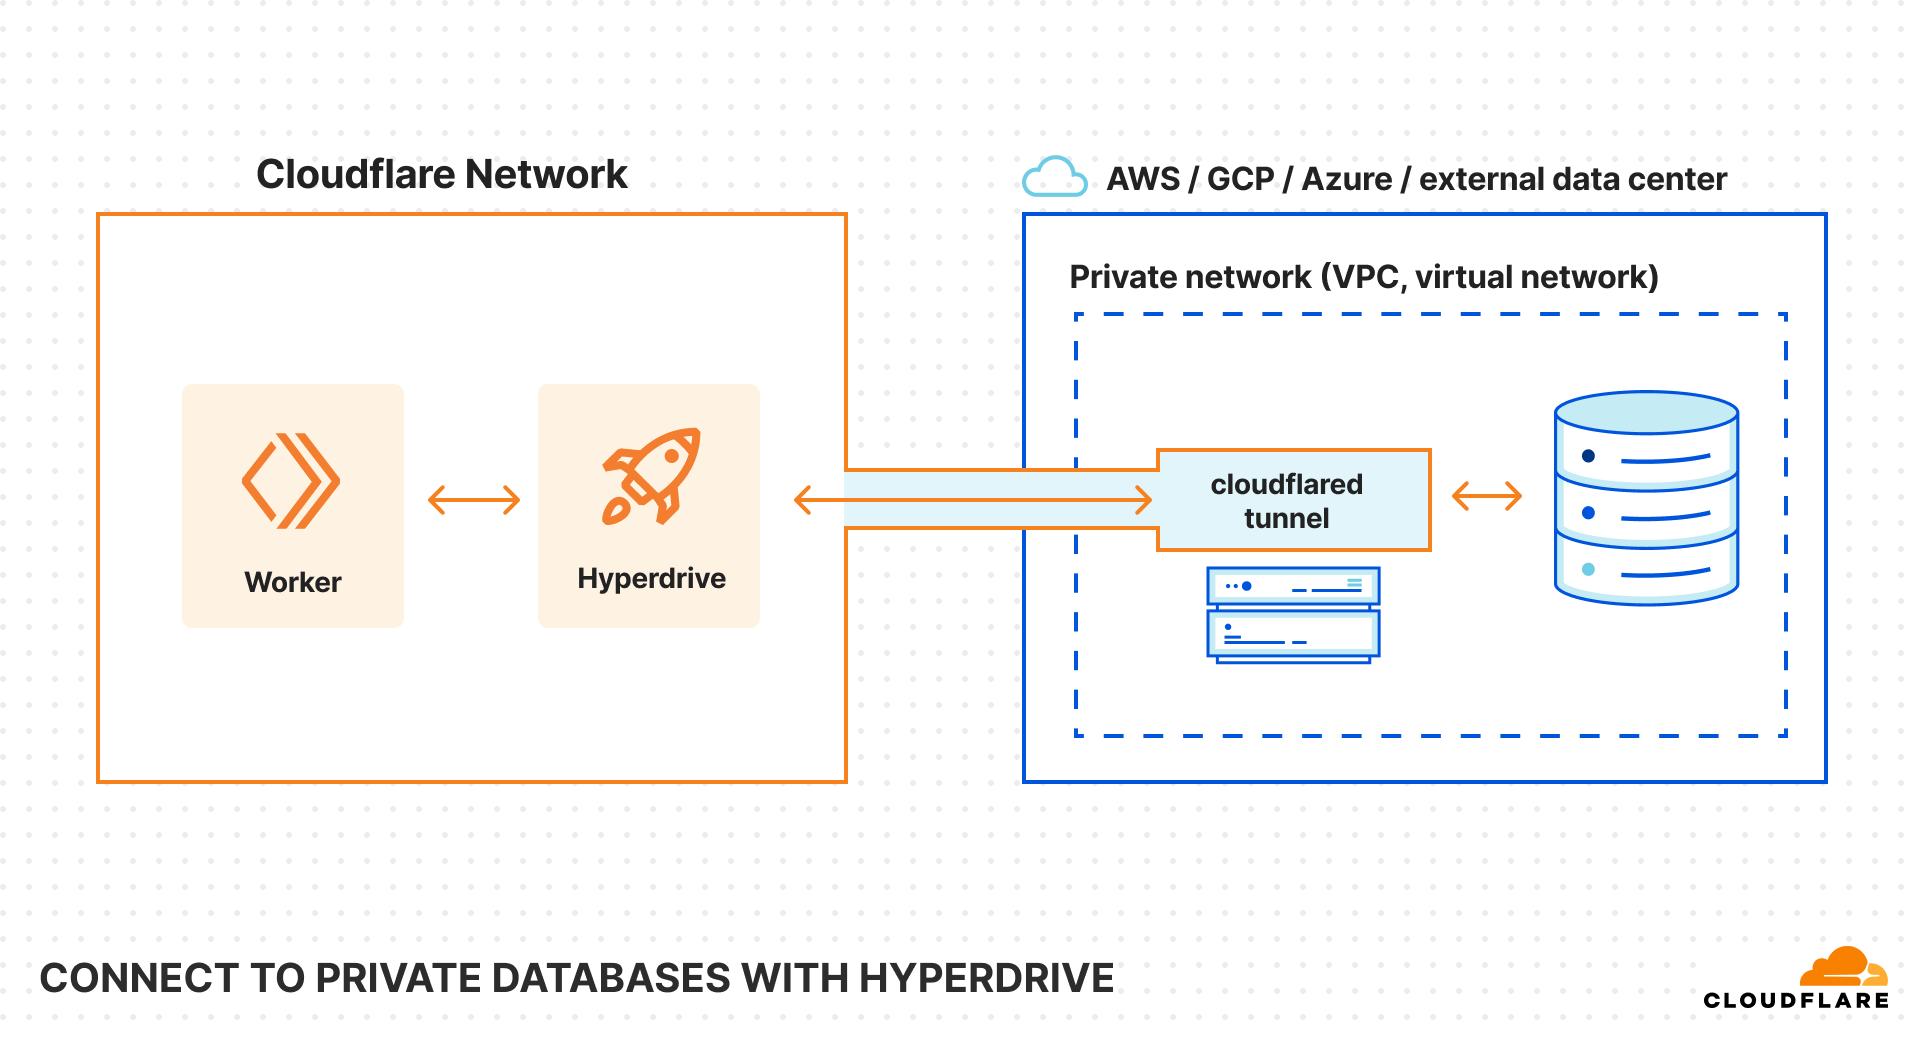
Starting today, you can now use Hyperdrive, Cloudflare Tunnels and Access together to securely connect to databases that are isolated in a private network.
Hyperdrive enables you to build on Workers with your existing regional databases. It accelerates database queries using Cloudflare’s network, caching data close to end users and pooling connections close to the database. But there’s been a major blocker preventing you from building with Hyperdrive: network isolation.
The majority of databases today aren’t publicly accessible on the Internet. Data is highly sensitive and placing databases within private networks like a virtual private cloud (VPC) keeps data secure. But to date, that has also meant that your data is held captive within your cloud provider, preventing you from building on Workers.
With this update, Hyperdrive makes it possible for you to build full-stack applications on Workers with your existing databases, network-isolated or not. Whether you’re using Amazon RDS, Amazon Aurora, Google Cloud SQL, Azure Database, or any other provider, Hyperdrive can connect to your databases and optimize your database connections to provide the fast performance you’ve come to expect with building on Workers.
Read the developer documentation to learn more about how to opt-in your Workers to try it today. If you encounter any bugs or want to report feedback, open an issue.
Build frontend applications on Workers with Static Asset Hosting
Starting today in open beta, you now can upload and serve HTML, CSS, and client-side JavaScript directly as part of your Worker. This means you can build dynamic, server-side rendered applications on Workers using popular frameworks such as Astro, Remix, Next.js and Svelte (full list here), with more coming soon.
If you’re wondering “What about Pages?” — rest assured, Pages will remain fully supported. We’ve heard from developers that as we’ve added new features to Workers and Pages, the choice of which product to use has become challenging. We’re closing this gap by bringing asset hosting, CI/CD and Preview URLs to Workers this Birthday Week.
To make the upfront choice Cloudflare Workers and Pages more transparent, we’ve created a compatibility matrix. Looking ahead, we plan to bridge the remaining gaps between Workers and Pages and provide ways to migrate your Pages projects to Workers.
Cloudflare joins OpenNext to deploy Next.js apps to Workers
Cloud providers shouldn’t lock you in. Like cloud compute and storage, open source frameworks should be portable — you should be able to deploy them to different cloud providers. The goal of the OpenNext project is to make sure you can deploy Next.js apps to any cloud platform, originally to AWS, and now Cloudflare. We’re excited to contribute to the OpenNext community, and give developers the freedom to run on the cloud that fits their applications needs (and budget) best.
Continuous Integration & Delivery (CI/CD) with Workers Builds
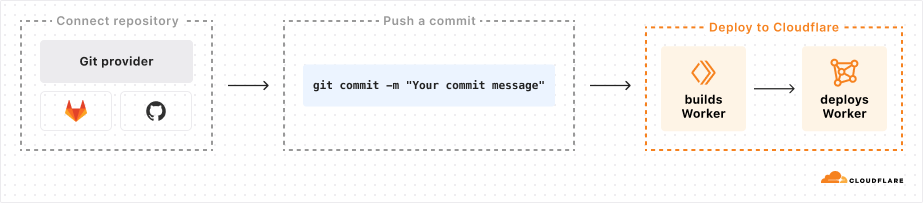
Now in open beta, you can connect a GitHub or GitLab repository to a Worker, and Cloudflare will automatically build and deploy your changes each time you push a commit. Workers Builds provides an integrated CI/CD workflow you can use to build and deploy everything from full-stack applications built with the most popular frameworks to simple static websites. Just add your build command and let Workers Builds take care of the rest.
While in open beta, Workers Builds is free to use, with a limit of one concurrent build per account, and unlimited build minutes per month. Once Workers Builds is Generally Available in early 2025, you will be billed based on the number of build minutes you use each month, and have a higher number of concurrent builds.
Workers Free
Workers Paid
Build minutes, open beta
Unlimited
Unlimited
Concurrent builds, open beta
1
1
Build minutes, general availability
3,000 minutes included per month
6,000 minutes included per month +$0.005 per additional build minute
Concurrent builds, general availability
1
6
Read the docs to learn more about how to deploy your first project with Workers Builds.
Workers preview URLs
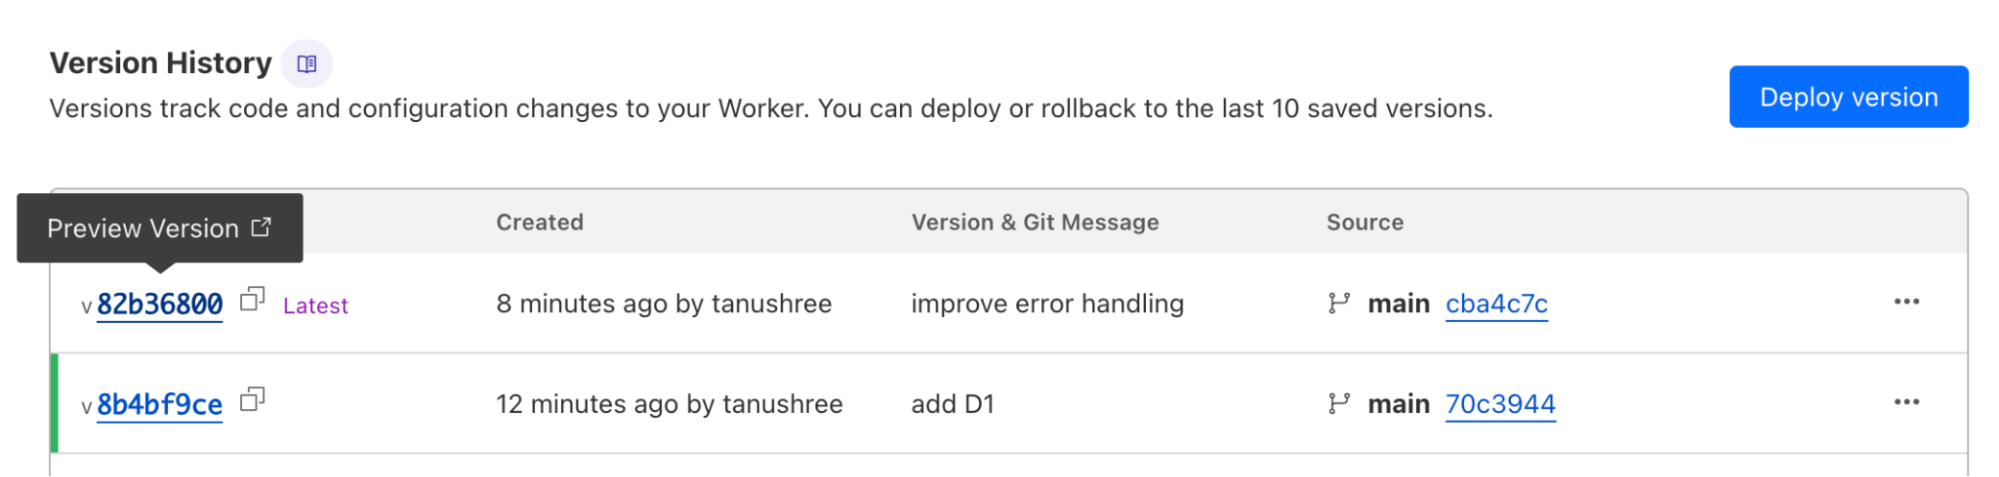
Each newly uploaded version of a Worker now automatically generates a preview URL. Preview URLs make it easier for you to collaborate with your team during development, and can be used to test and identify issues in a preview environment before they are deployed to production.
When you upload a version of your Worker via the Wrangler CLI, Wrangler will display the preview URL once your upload succeeds. You can also find preview URLs for each version of your Worker in the Cloudflare dashboard:
Preview URLs for Workers are similar to Pages preview deployments — they run on your Worker’s workers.dev subdomain and allow you to view changes applied on a new version of your application before the changes are deployed.
Safely release to production with Gradual Deployments
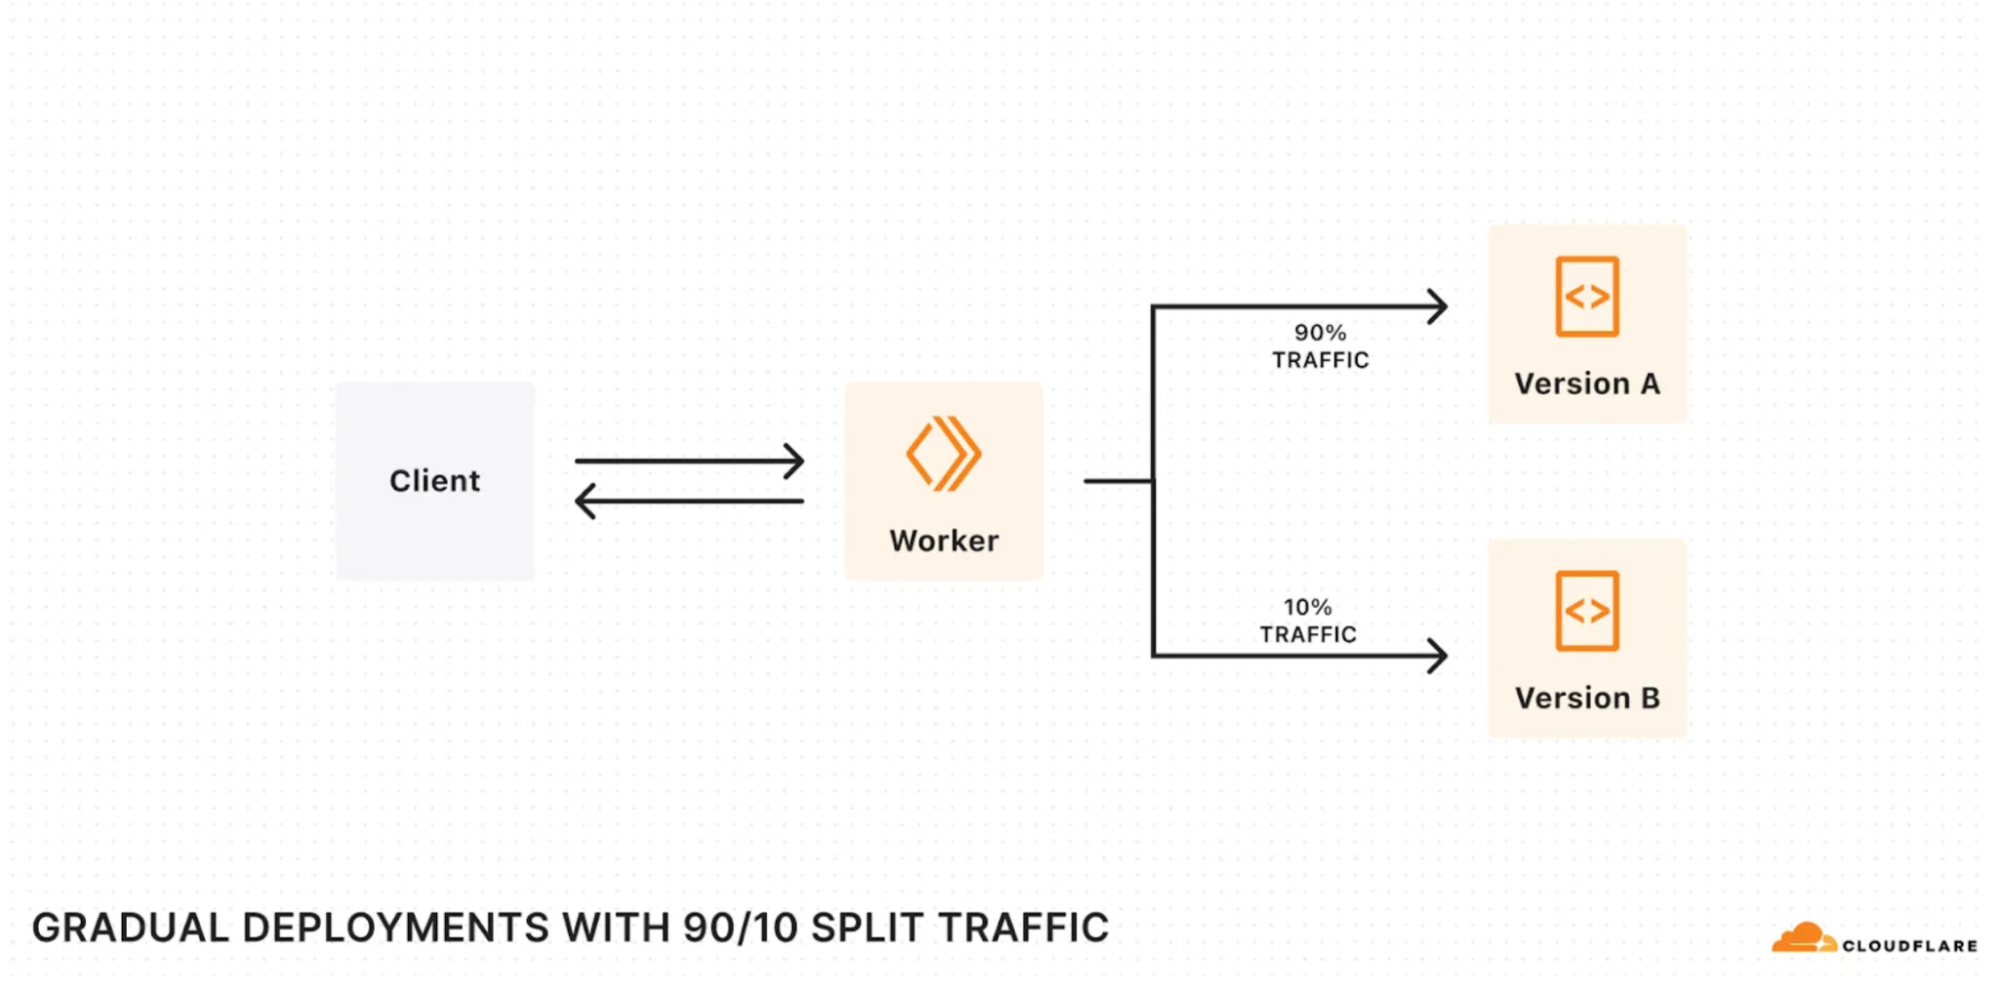
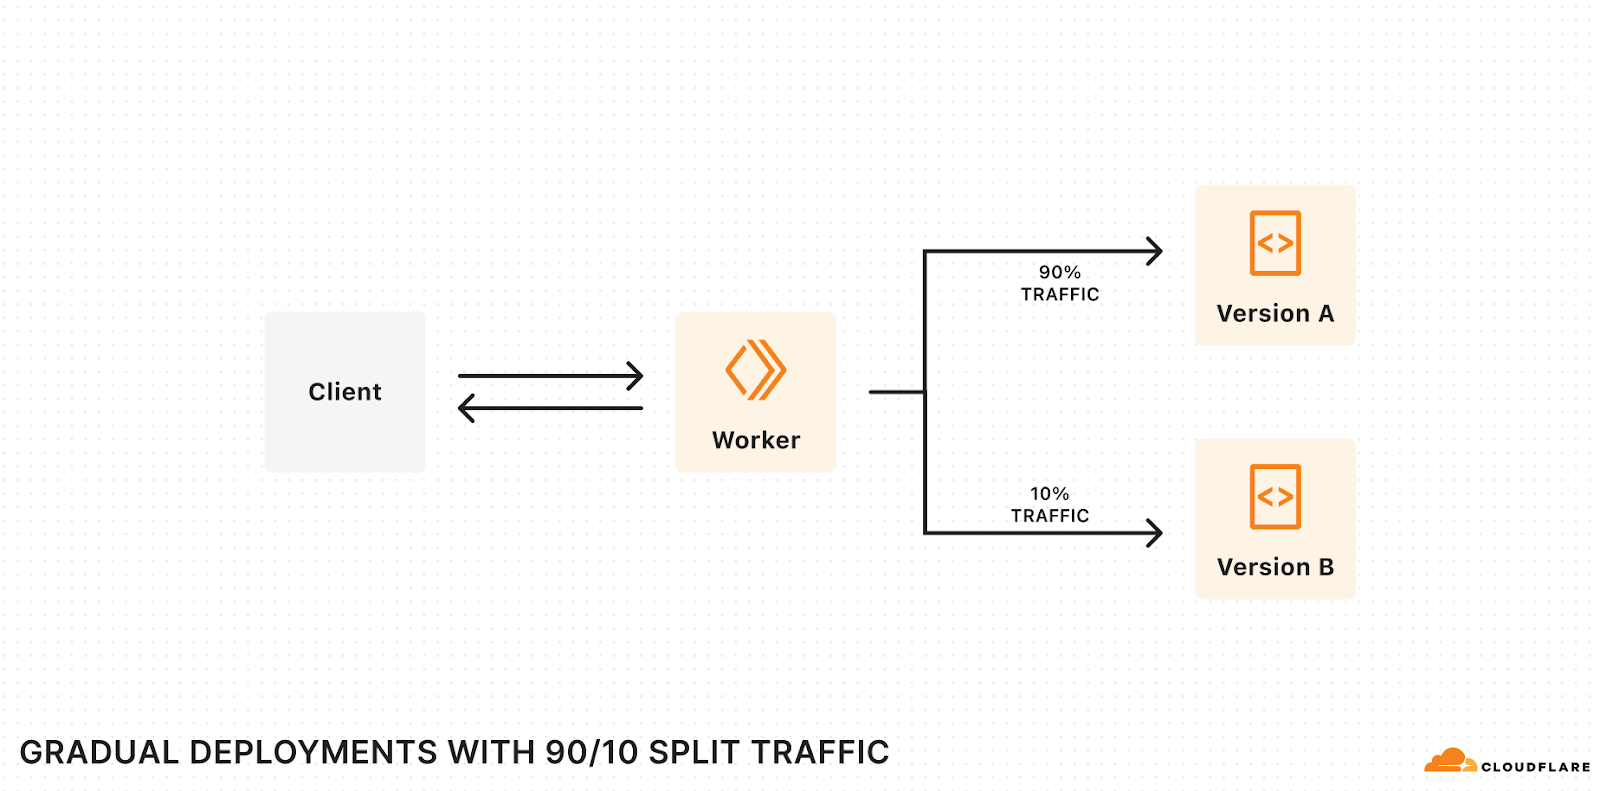
At Developer Week, we launched Gradual Deployments for Workers and Durable Objects to make it safer and easier to deploy changes to your applications. Gradual Deployments is now GA — we have been using it ourselves at Cloudflare for mission-critical services built on Workers since early 2024.
Gradual deployments can help you stay on top of availability SLAs and minimize application downtime by surfacing issues early. Internally at Cloudflare, every single service built on Workers uses gradual deployments to roll out new changes. Each new version gets released in stages —– 0.05%, 0.5%, 3%, 10%, 25%, 50%, 75% and 100% with time to soak between each stage. Throughout the roll-out, we keep an eye on metrics (which are often instrumented with Workers Analytics Engine!) and we roll back if we encounter issues.
Using gradual deployments is as simple as swapping out the wrangler commands, API endpoints, and/or using “Save version” in the code editor that is built into the Workers dashboard. Read the developer documentation to learn more and get started.
Queues is GA, with higher throughput and concurrency limits
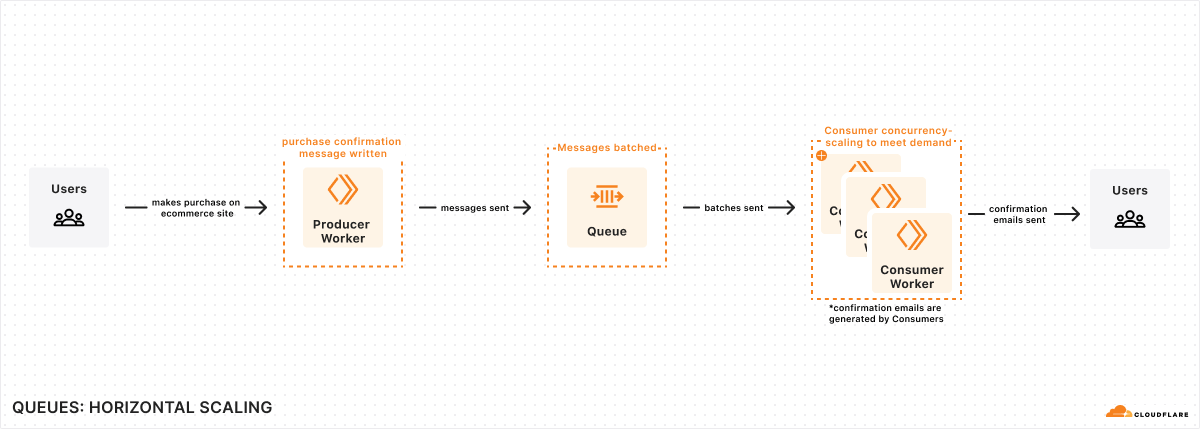
Queues let a developer decouple their Workers into event driven services. Producer Workers write events to a Queue, and consumer Workers are invoked to take actions on the events. For example, you can use a Queue to decouple an e-commerce website from a service which sends purchase confirmation emails to users.
Throughput and concurrency limits for Queues are now significantly higher, which means you can push more messages through a Queue, and consume them faster.
Throughput: Each queue can now process 5000 messages per second (previously 400 per second).
Concurrency: Each queue can now have up to 250 concurrent consumers (previously 20 concurrent consumers).
HTTP Pull consumers allow messages to be consumed outside Workers, with zero data egress costs.
Queues can be used by any developer on a Workers Paid plan. Head over to our getting startedguide to start building with Queues.
Event notifications for R2 is now GA
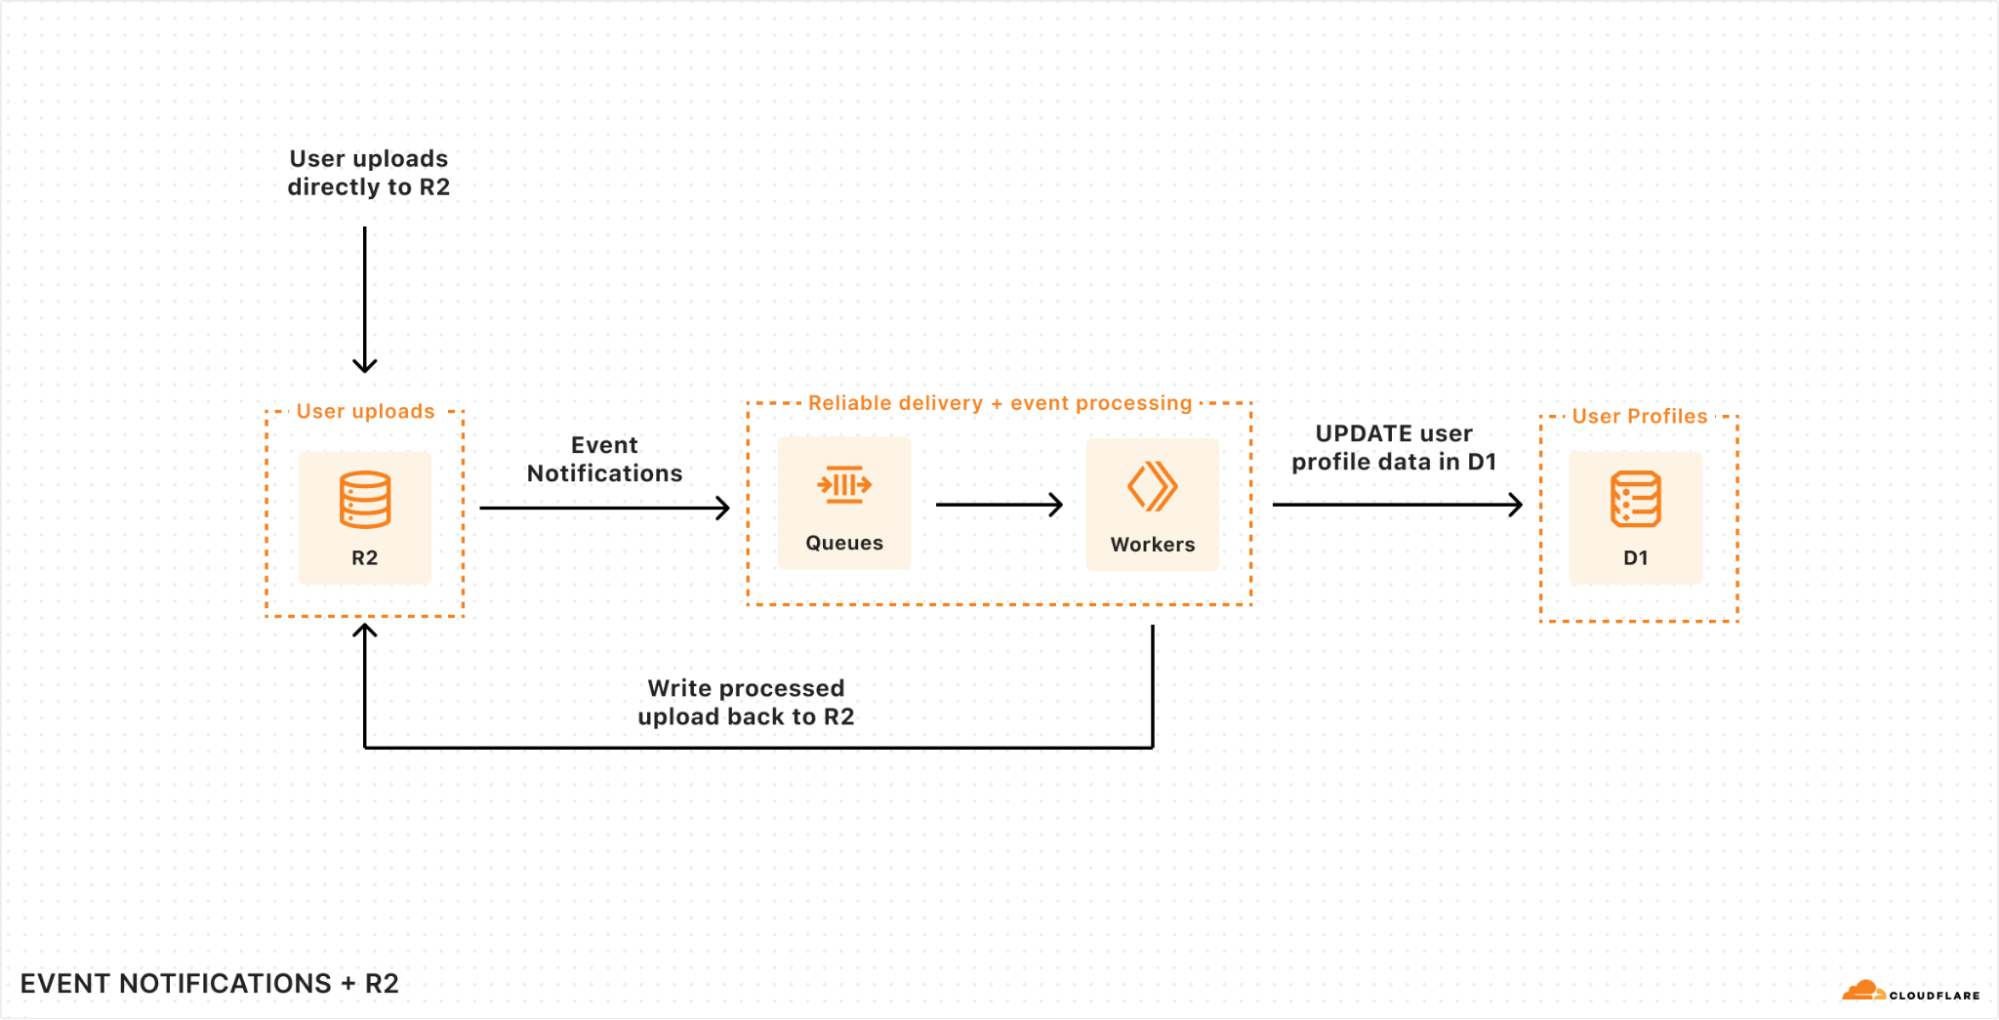
We’re excited to announce that event notifications for R2 is now generally available. Whether it’s kicking off image processing after a user uploads a file or triggering a sync to an external data warehouse when new analytics data is generated, many applications need to be able to reliably respond when events happen. Event notifications for Cloudflare R2 give you the ability to build event-driven applications and workflows that react to changes in your data.
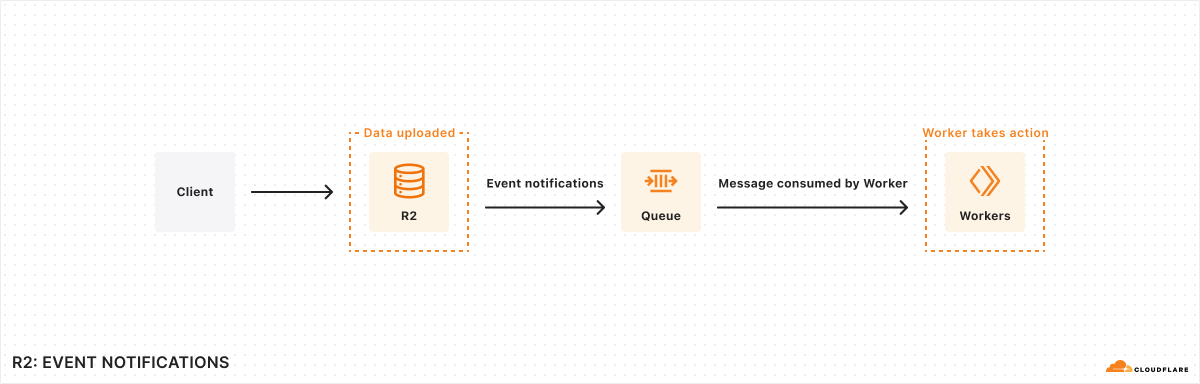
Here’s how it works: When data in your R2 bucket changes, event notifications are sent to your queue. You can consume these notifications with a consumer Worker or pull them over HTTP from outside of Cloudflare Workers.
Since we introduced event notifications in open beta earlier this year, we’ve made significant improvements based on your feedback:
We increased reliability of event notifications with throughput improvements from Queues. R2 event notifications can now scale to thousands of writes per second.
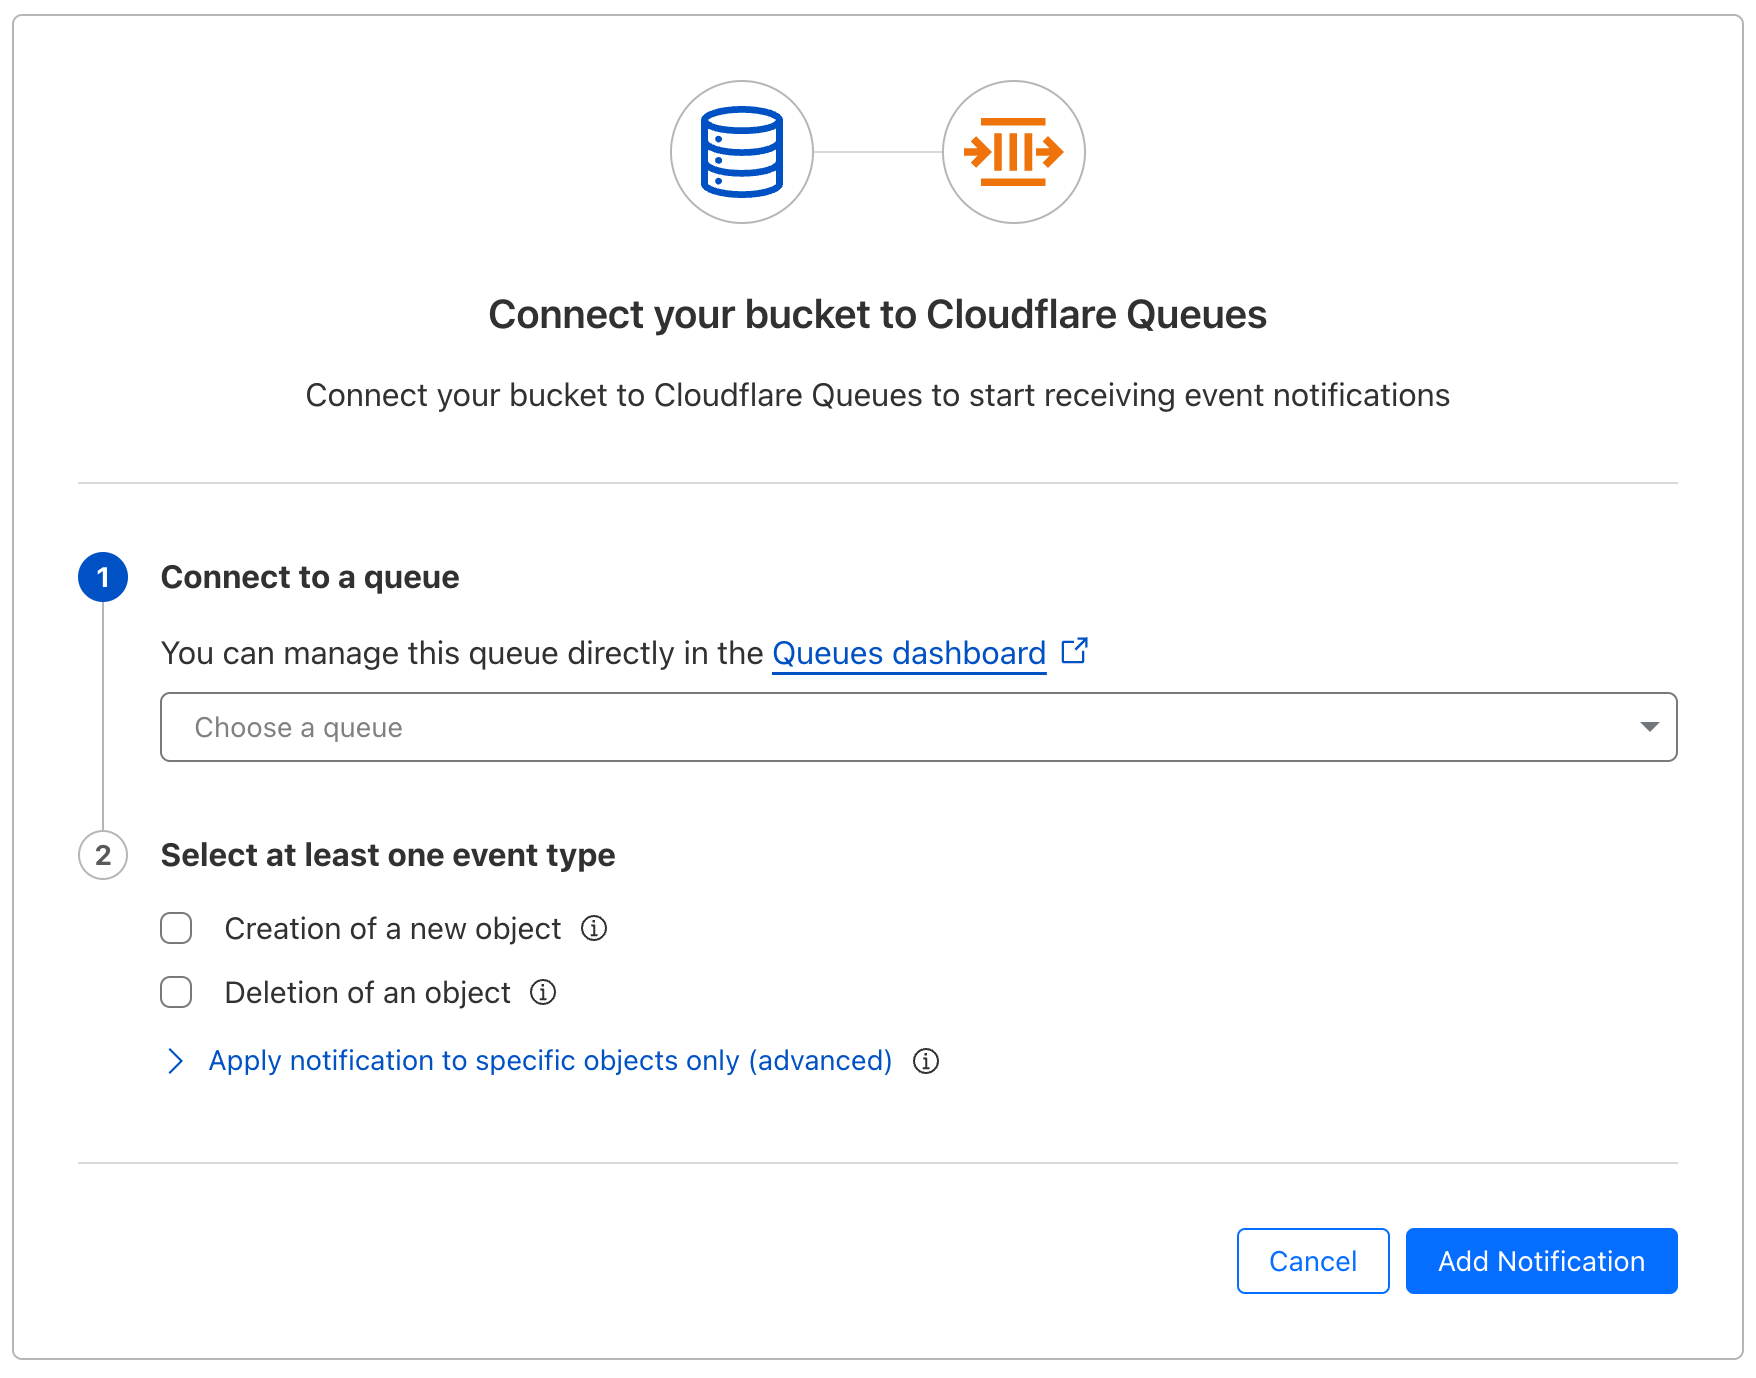
You can now configure event notifications directly from the Cloudflare dashboard (in addition to Wrangler).
You can now set up multiple notification rules for a single queue on a bucket.
Visit our documentation to learn about how to set up event notifications for your R2 buckets.
Removing the serverless microservices tax: No more request fees for Service Bindings and Tail Workers
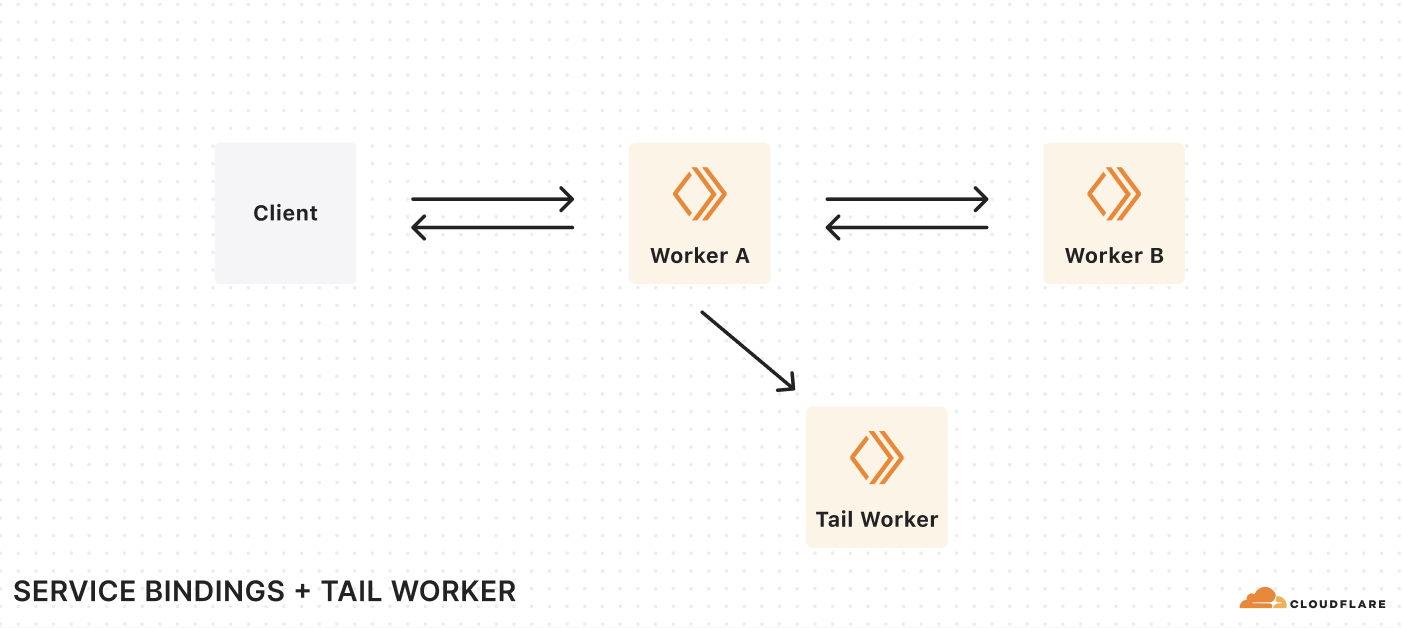
Earlier this year, we quietly changed Workers pricing to lower your costs. As of July 2024, you are no longer charged for requests between Workers on your account made via Service Bindings, or for invocations of Tail Workers. For example, let’s say you have the following chain of Workers:
Each request from a client results in three Workers invocations. Previously, we charged you for each of these invocations, plus the CPU time for each of these Workers. With this change, we only charge you for the first request from the client, plus the CPU time used by each Worker.
This eliminates the additional cost of breaking a monolithic serverless app into microservices. In 2023, we introduced new pricing based on CPU time, rather than duration, so you don’t have to worry about being billed for time spent waiting on I/O. This includes I/O to other Workers. With this change, you’re only billed for the first request in the chain, eliminating the other additional cost of using multiple Workers.
Image optimization is available to everyone for free — no subscription needed
Starting today, you can use Cloudflare Images for free to optimize your images with up to 5,000 transformations per month.
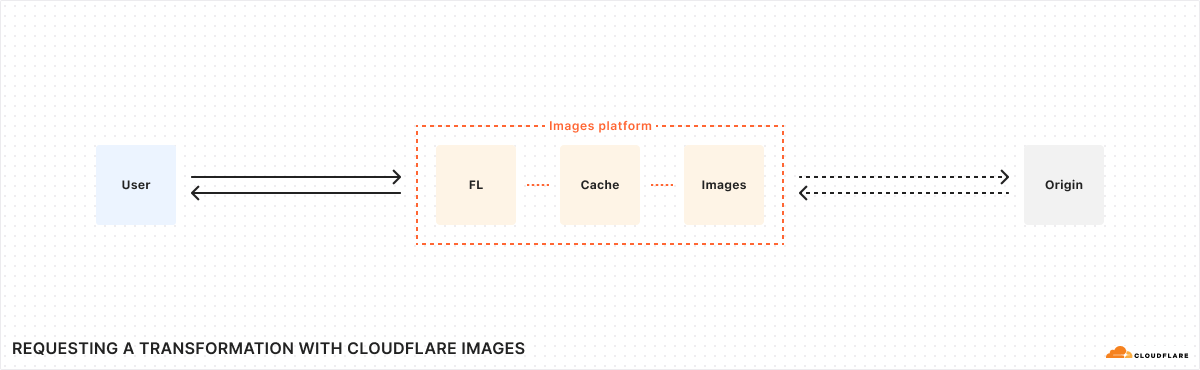
Large, oversized images can throttle your application speed and page load times. We built Cloudflare Images to let you dynamically optimize images in the correct dimensions and formats for each use case, all while storing only the original image.
In the spirit of Birthday Week, we’re making image optimization available to everyone with a Cloudflare account, no subscription needed. You’ll be able to use Images to transform images that are stored outside of Images, such as in R2.
Transformations are served from your zone through a specially formatted URL with parameters that specify how an image should be optimized. For example, the transformation URL below uses the format parameter to automatically serve the image in the most optimal format for the requesting browser:
This means that the original PNG image may be served as AVIF to one user and WebP to another. Without a subscription, transforming images from remote sources is free up to 5,000 unique transformations per month. Once you exceed this limit, any already cached transformations will continue to be served, but you’ll need a paid Images plan to request new transformations or to purchase storage within Images.
Dive deep into more announcements from Builder Day
We shipped so much that we couldn’t possibly fit it all in one blog post. These posts dive into the technical details of what we’re announcing at Builder Day:
Cloudflare is for builders, and everything we’re announcing at Builder Day, you can start building with right away. We’re now offering $250,000 in credits to use on our Developer Platform to qualified startups, so that you can get going even faster, and become the next company to reach hypergrowth scale with a small team, and not waste time provisioning infrastructure and doing undifferentiated heavy lifting. Focus on shipping, and we’ll take care of the rest.
Traditional cloud storage is inherently slow, because it is normally accessed over a network and must carefully synchronize across many clients that could be accessing the same data. But what if we could instead put your application code deep into the storage layer, such that your code runs directly on the machine where the data is stored, and the database itself executes as a local library embedded inside your application?
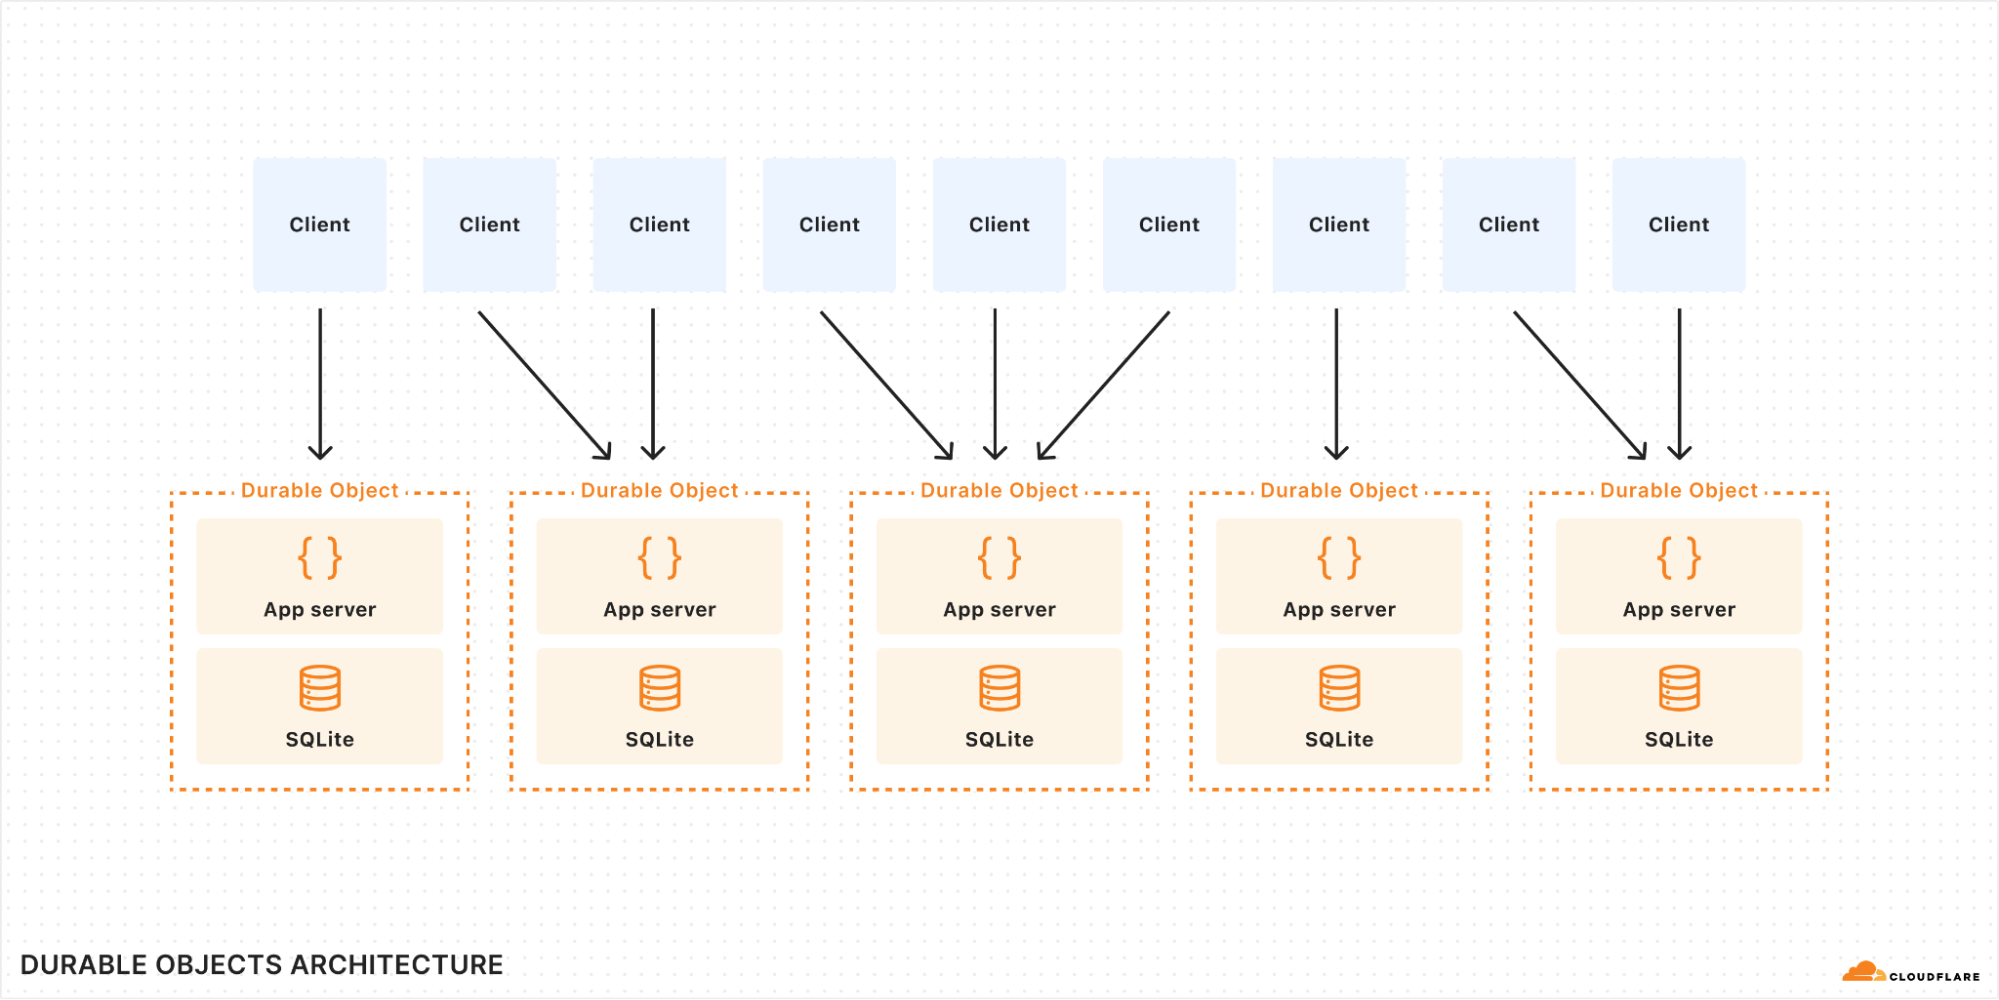
Durable Objects (DO) are a novel approach to cloud computing which accomplishes just that: Your application code runs exactly where the data is stored. Not just on the same machine: your storage lives in the same thread as the application, requiring not even a context switch to access. With proper use of caching, storage latency is essentially zero, while nevertheless being durable and consistent.
Until today, DOs only offered key/value oriented storage. But now, they support a full SQL query interface with tables and indexes, through the power of SQLite.
SQLite is the most-used SQL database implementation in the world, with billions of installations. It’s on practically every phone and desktop computer, and many embedded devices use it as well. It’s known to be blazingly fast and rock solid. But it’s been less common on the server. This is because traditional cloud architecture favors large distributed databases that live separately from application servers, while SQLite is designed to run as an embedded library. In this post, we’ll show you how Durable Objects turn this architecture on its head and unlock the full power of SQLite in the cloud.
Refresher: what are Durable Objects?
Durable Objects (DOs) are a part of the Cloudflare Workers serverless platform. A DO is essentially a small server that can be addressed by a unique name and can keep state both in-memory and on-disk. Workers running anywhere on Cloudflare’s network can send messages to a DO by its name, and all messages addressed to the same name — from anywhere in the world — will find their way to the same DO instance.
DOs are intended to be small and numerous. A single application can create billions of DOs distributed across our global network. Cloudflare automatically decides where a DO should live based on where it is accessed, automatically starts it up as needed when requests arrive, and shuts it down when idle. A DO has in-memory state while running and can also optionally store long-lived durable state. Since there is exactly one DO for each name, a DO can be used to coordinate between operations on the same logical object.
For example, imagine a real-time collaborative document editor application. Many users may be editing the same document at the same time. Each user’s changes must be broadcast to other users in real time, and conflicts must be resolved. An application built on DOs would typically create one DO for each document. The DO would receive edits from users, resolve conflicts, broadcast the changes back out to other users, and keep the document content updated in its local storage.
DOs are especially good at real-time collaboration, but are by no means limited to this use case. They are general-purpose servers that can implement any logic you desire to serve requests. Even more generally, DOs are a basic building block for distributed systems.
When using Durable Objects, it’s important to remember that they are intended to scale out, not up. A single object is inherently limited in throughput since it runs on a single thread of a single machine. To handle more traffic, you create more objects. This is easiest when different objects can handle different logical units of state (like different documents, different users, or different “shards” of a database), where each unit of state has low enough traffic to be handled by a single object. But sometimes, a lot of traffic needs to modify the same state: consider a vote counter with a million users all trying to cast votes at once. To handle such cases with Durable Objects, you would need to create a set of objects that each handle a subset of traffic and then replicate state to each other. Perhaps they use CRDTs in a gossip network, or perhaps they implement a fan-in/fan-out approach to a single primary object. Whatever approach you take, Durable Objects make it fast and easy to create more stateful nodes as needed.
Why is SQLite-in-DO so fast?
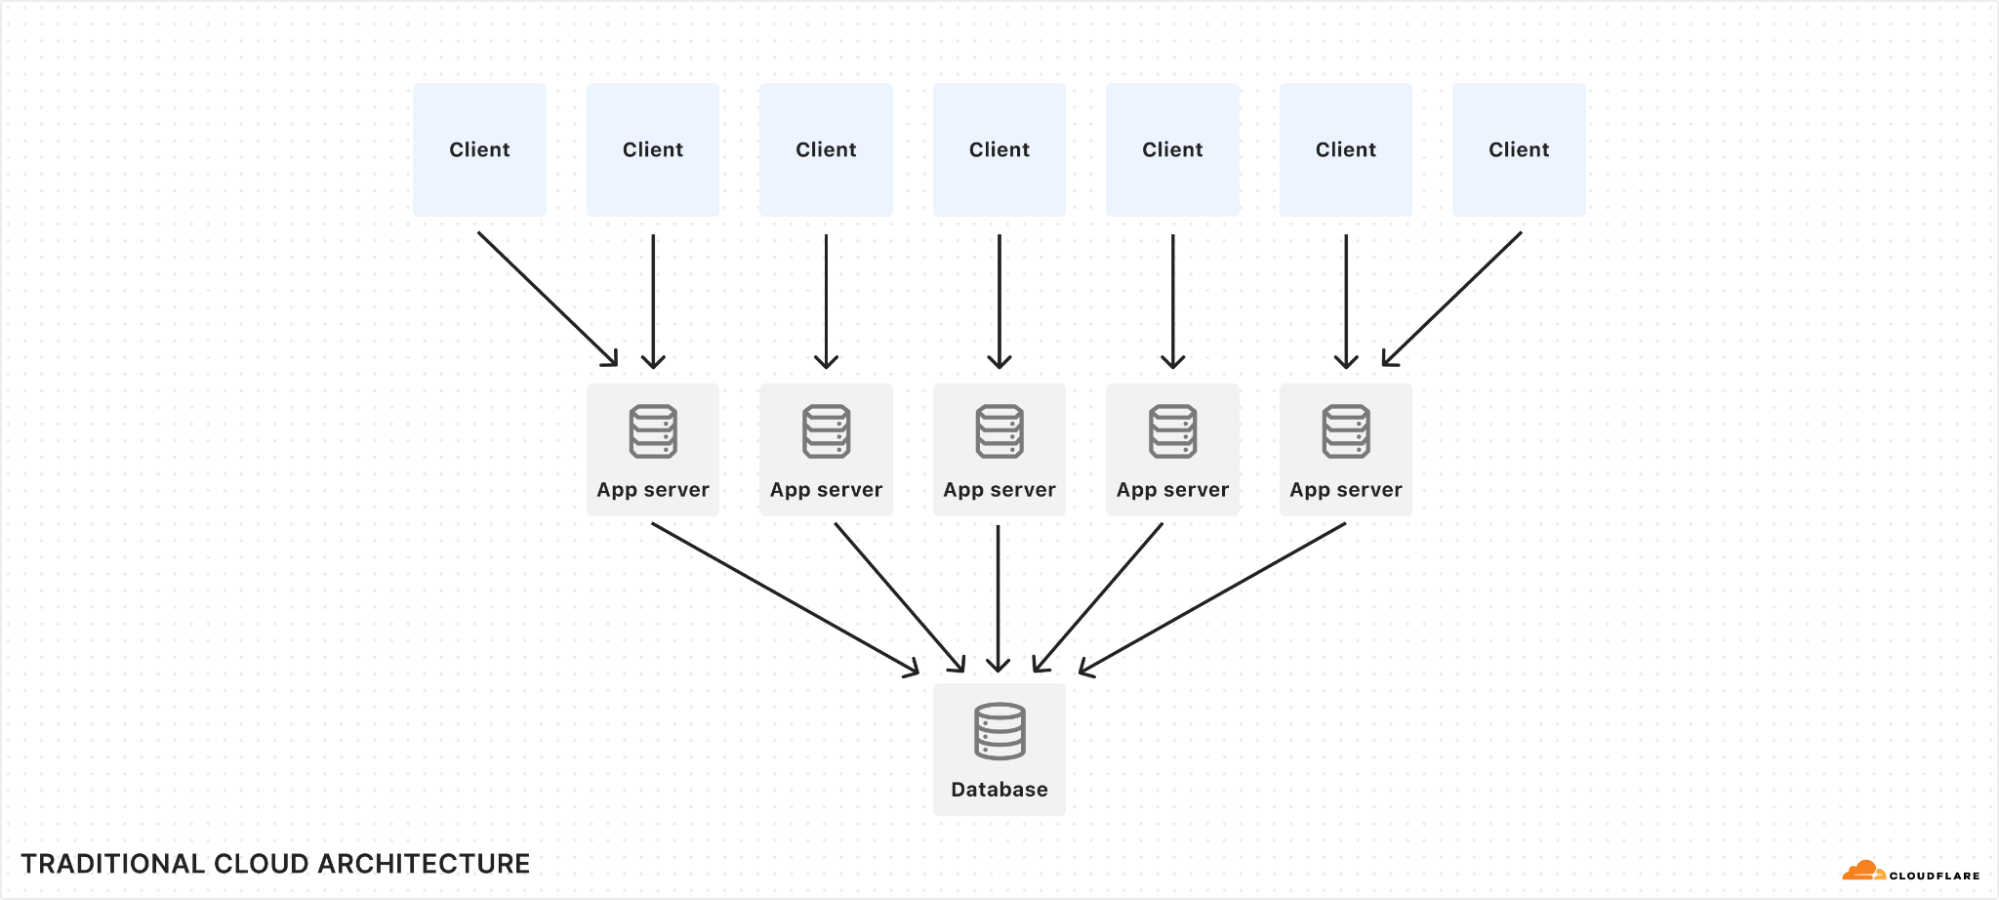
In traditional cloud architecture, stateless application servers run business logic and communicate over the network to a database. Even if the network is local, database requests still incur latency, typically measured in milliseconds.
When a Durable Object uses SQLite, SQLite is invoked as a library. This means the database code runs not just on the same machine as the DO, not just in the same process, but in the very same thread. Latency is effectively zero, because there is no communication barrier between the application and SQLite. A query can complete in microseconds.
Reads and writes are synchronous
The SQL query API in DOs does not require you to await results — they are returned synchronously:
// No awaits!
let cursor = sql.exec("SELECT name, email FROM users");
for (let user of cursor) {
  console.log(user.name, user.email);
}
This may come as a surprise to some. Querying a database is I/O, right? I/O should always be asynchronous, right? Isn’t this a violation of the natural order of JavaScript?
It’s OK! The database content is probably cached in memory already, and SQLite is being called as a library in the same thread as the application, so the query often actually won’t spend any time at all waiting for I/O. Even if it does have to go to disk, it’s a local SSD. You might as well consider the local disk as just another layer in the memory cache hierarchy: L5 cache, if you will. In any case, it will respond quickly.
Meanwhile, synchronous queries provide some big benefits. First, the logistics of asynchronous event loops have a cost, so in the common case where the data is already in memory, a synchronous query will actually complete faster than an async one.
More importantly, though, synchronous queries help you avoid subtle bugs. Any time your application awaits a promise, it’s possible that some other code executes while you wait. The state of the world may have changed by the time your await completes. Maybe even other SQL queries were executed. This can lead to subtle bugs that are hard to reproduce because they require events to happen at just the wrong time. With a synchronous API, though, none of that can happen. Your code always executes in the order you wrote it, uninterrupted.
Fast writes with Output Gates
Database experts might have a deeper objection to synchronous queries: Yes, caching may mean we can perform reads and writes very fast. However, in the case of a write, just writing to cache isn’t good enough. Before we return success to our client, we must confirm that the write is actually durable, that is, it has actually made it onto disk or network storage such that it cannot be lost if the power suddenly goes out.
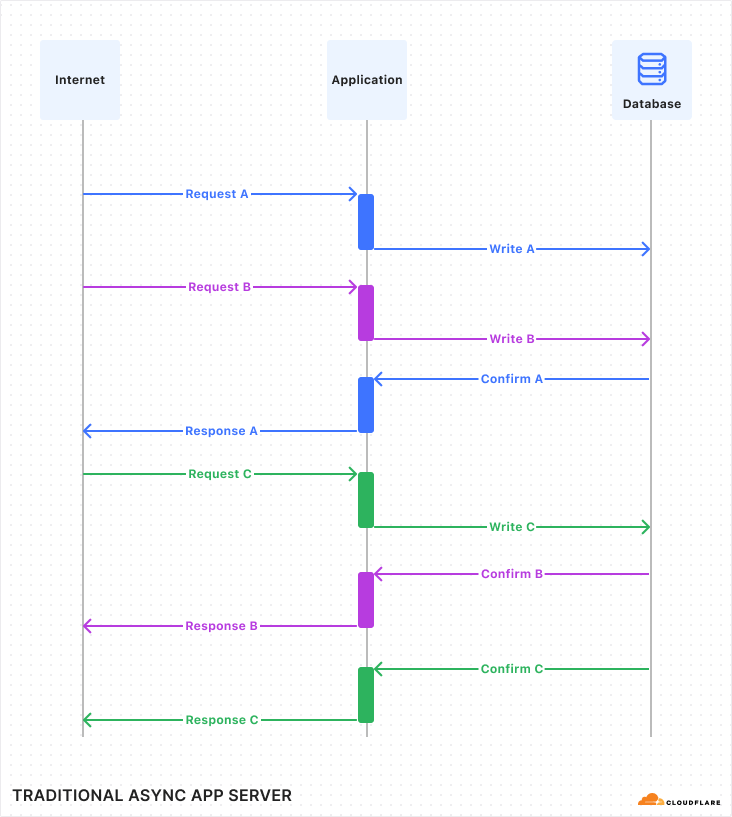
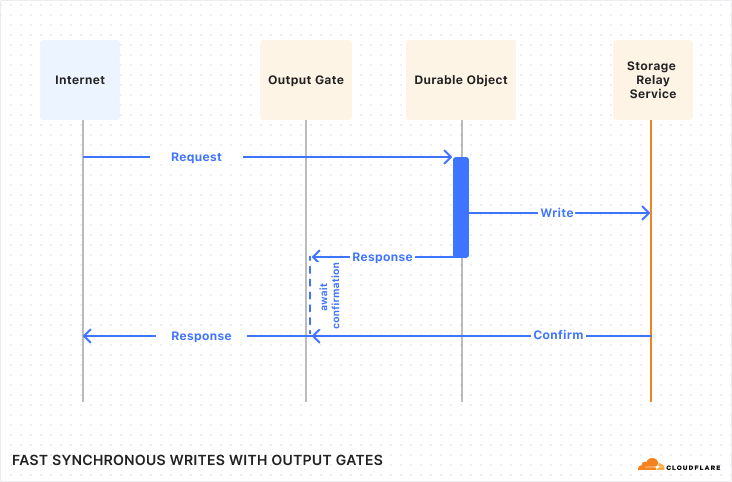
Normally, a database would confirm all writes before returning to the application. So if the query is successful, it is confirmed. But confirming writes can be slow, because it requires waiting for the underlying storage medium to respond. Normally, this is OK because the write is performed asynchronously, so the program can go on and work on other things while it waits for the write to finish. It looks kind of like this:
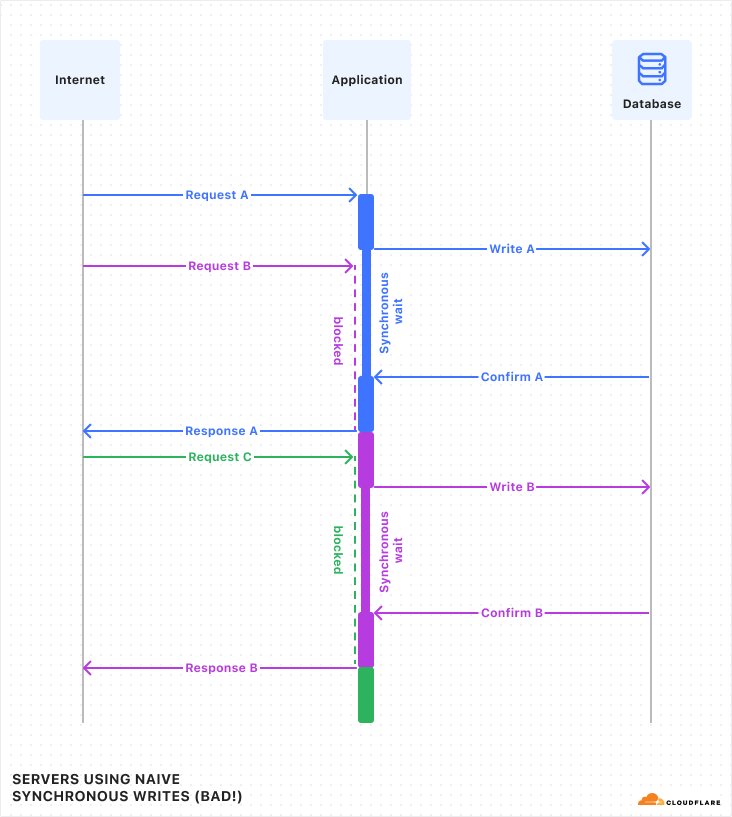
But I just told you that in Durable Objects, writes are synchronous. While a synchronous call is running, no other code in the program can run (because JavaScript does not have threads). This is convenient, as mentioned above, because it means you don’t need to worry that the state of the world may have changed while you were waiting. However, if write queries have to wait a while, and the whole program must pause and wait for them, then throughput will suffer.
Luckily, in Durable Objects, writes do not have to wait, due to a little trick we call “Output Gates”.
In DOs, when the application issues a write, it continues executing without waiting for confirmation. However, when the DO then responds to the client, the response is blocked by the “Output Gate”. This system holds the response until all storage writes relevant to the response have been confirmed, then sends the response on its way. In the rare case that the write fails, the response will be replaced with an error and the Durable Object itself will restart. So, even though the application constructed a “success” response, nobody can ever see that this happened, and thus nobody can be misled into believing that the data was stored.
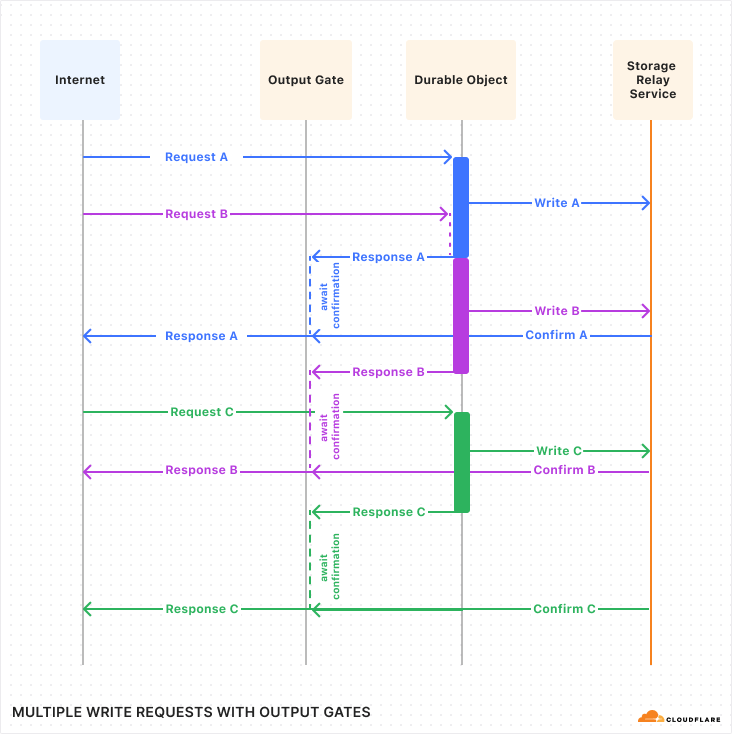
Let’s see what this looks like with multiple requests:
If you compare this against the first diagram above, you should notice a few things:
The timing of requests and confirmations are the same.
But, all responses were sent to the client sooner than in the first diagram. Latency was reduced! This is because the application is able to work on constructing the response in parallel with the storage layer confirming the write.
Request handling is no longer interleaved between the three requests. Instead, each request runs to completion before the next begins. The application does not need to worry, during the handling of one request, that its state might change unexpectedly due to a concurrent request.
With Output Gates, we get the ease-of-use of synchronous writes, while also getting lower latency and no loss of throughput.
N+1 selects? No problem.
Zero-latency queries aren’t just faster, they allow you to structure your code differently, often making it simpler. A classic example is the “N+1 selects” or “N+1 queries” problem. Let’s illustrate this problem with an example:
// N+1 SELECTs example

// Get the 100 most-recently-modified docs.
let docs = sql.exec(`
  SELECT title, authorId FROM documents
  ORDER BY lastModified DESC
  LIMIT 100
`).toArray();

// For each returned document, get the author name from the users table.
for (let doc of docs) {
  doc.authorName = sql.exec(
      "SELECT name FROM users WHERE id = ?", doc.authorId).one().name;
}
If you are an experienced SQL user, you are probably cringing at this code, and for good reason: this code does 101 queries! If the application is talking to the database across a network with 5ms latency, this will take 505ms to run, which is slow enough for humans to notice.
// Do it all in one query with a join?
let docs = sql.exec(`
  SELECT documents.title, users.name
  FROM documents JOIN users ON documents.authorId = users.id
  ORDER BY documents.lastModified DESC
  LIMIT 100
`).toArray();
Here we’ve used SQL features to turn our 101 queries into one query. Great! Except, what does it mean? We used an inner join, which is not to be confused with a left, right, or cross join. What’s the difference? Honestly, I have no idea! I had to look up joins just to write this example and I’m already confused.
Well, good news: You don’t need to figure it out. Because when using SQLite as a library, the first example above works just fine. It’ll perform about the same as the second fancy version.
More generally, when using SQLite as a library, you don’t have to learn how to do fancy things in SQL syntax. Your logic can be in regular old application code in your programming language of choice, orchestrating the most basic SQL queries that are easy to learn. It’s fine. The creators of SQLite have made this point themselves.
Point-in-Time Recovery
While not necessarily related to speed, SQLite-backed Durable Objects offer another feature: any object can be reverted to the state it had at any point in time in the last 30 days. So if you accidentally execute a buggy query that corrupts all your data, don’t worry: you can recover. There’s no need to opt into this feature in advance; it’s on by default for all SQLite-backed DOs. See the docs for details.
How do I use it?
Let’s say we’re an airline, and we are implementing a way for users to choose their seats on a flight. We will create a new Durable Object for each flight. Within that DO, we will use a SQL table to track the assignments of seats to passengers. The code might look something like this:
import {DurableObject} from "cloudflare:workers";

// Manages seat assignment for a flight.
//
// This is an RPC interface. The methods can be called remotely by other Workers
// running anywhere in the world. All Workers that specify same object ID
// (probably based on the flight number and date) will reach the same instance of
// FlightSeating.
export class FlightSeating extends DurableObject {
  sql = this.ctx.storage.sql;

  // Application calls this when the flight is first created to set up the seat map.
  initializeFlight(seatList) {
    this.sql.exec(`
      CREATE TABLE seats (
        seatId TEXT PRIMARY KEY,  -- e.g. "3B"
        occupant TEXT             -- null if available
      )
    `);

    for (let seat of seatList) {
      this.sql.exec(`INSERT INTO seats VALUES (?, null)`, seat);
    }
  }

  // Get a list of available seats.
  getAvailable() {
    let results = [];

    // Query returns a cursor.
    let cursor = this.sql.exec(`SELECT seatId FROM seats WHERE occupant IS NULL`);

    // Cursors are iterable.
    for (let row of cursor) {
      // Each row is an object with a property for each column.
      results.push(row.seatId);
    }

    return results;
  }

  // Assign passenger to a seat.
  assignSeat(seatId, occupant) {
    // Check that seat isn't occupied.
    let cursor = this.sql.exec(`SELECT occupant FROM seats WHERE seatId = ?`, seatId);
    let result = [...cursor][0];  // Get the first result from the cursor.
    if (!result) {
      throw new Error("No such seat: " + seatId);
    }
    if (result.occupant !== null) {
      throw new Error("Seat is occupied: " + seatId);
    }

    // If the occupant is already in a different seat, remove them.
    this.sql.exec(`UPDATE seats SET occupant = null WHERE occupant = ?`, occupant);

    // Assign the seat. Note: We don't have to worry that a concurrent request may
    // have grabbed the seat between the two queries, because the code is synchronous
    // (no `await`s) and the database is private to this Durable Object. Nothing else
    // could have changed since we checked that the seat was available earlier!
    this.sql.exec(`UPDATE seats SET occupant = ? WHERE seatId = ?`, occupant, seatId);
  }
}
(With just a little more code, we could extend this example to allow clients to subscribe to seat changes with WebSockets, so that if multiple people are choosing their seats at the same time, they can see in real time as seats become unavailable. But, that’s outside the scope of this blog post, which is just about SQL storage.)
Then in wrangler.toml, define a migration setting up your DO class like usual, but instead of using new_classes, use new_sqlite_classes:
[[migrations]]
tag = "v1"
new_sqlite_classes = ["FlightSeating"]
SQLite-backed objects also support the existing key/value-based storage API: KV data is stored into a hidden table in the SQLite database. So, existing applications built on DOs will work when deployed using SQLite-backed objects.
However, because SQLite-backed objects are based on an all-new storage backend, it is currently not possible to switch an existing deployed DO class to use SQLite. You must ask for SQLite when initially deploying the new DO class; you cannot change it later. We plan to begin migrating existing DOs to the new storage backend in 2025.
Pricing
We’ve kept pricing for SQLite-in-DO similar to D1, Cloudflare’s serverless SQL database, by billing for SQL queries (based on rows) and SQL storage. SQL storage per object is limited to 1 GB during the beta period, and will be increased to 10 GB on general availability. DO requests and duration billing are unchanged and apply to all DOs regardless of storage backend.
During the initial beta, billing is not enabled for SQL queries (rows read and rows written) and SQL storage. SQLite-backed objects will incur charges for requests and duration. We plan to enable SQL billing in the first half of 2025 with advance notice.
Workers Paid
Rows read
First 25 billion / month included + $0.001 / million rows
Rows written
First 50 million / month included + $1.00 / million rows
SQL storage
5 GB-month + $0.20/ GB-month
For more on how to use SQLite-in-Durable Objects, check out the documentation.
What about D1?
Cloudflare Workers already offers another SQLite-backed database product: D1. In fact, D1 is itself built on SQLite-in-DO. So, what’s the difference? Why use one or the other?
In short, you should think of D1 as a more “managed” database product, while SQLite-in-DO is more of a lower-level “compute with storage” building block.
D1 fits into a more traditional cloud architecture, where stateless application servers talk to a separate database over the network. Those application servers are typically Workers, but could also be clients running outside of Cloudflare. D1 also comes with a pre-built HTTP API and managed observability features like query insights. With D1, where your application code and SQL database queries are not colocated like in SQLite-in-DO, Workers has Smart Placement to dynamically run your Worker in the best location to reduce total request latency, considering everything your Worker talks to, including D1. By the end of 2024, D1 will support automatic read replication for scalability and low-latency access around the world. If this managed model appeals to you, use D1.
Durable Objects require a bit more effort, but in return, give you more power. With DO, you have two pieces of code that run in different places: a front-end Worker which routes incoming requests from the Internet to the correct DO, and the DO itself, which runs on the same machine as the SQLite database. You may need to think carefully about which code to run where, and you may need to build some of your own tooling that exists out-of-the-box with D1. But because you are in full control, you can tailor the solution to your application’s needs and potentially achieve more.
Under the hood: Storage Relay Service
When Durable Objects first launched in 2020, it offered only a simple key/value-based interface for durable storage. Under the hood, these keys and values were stored in a well-known off-the-shelf database, with regional instances of this database deployed to locations in our data centers around the world. Durable Objects in each region would store their data to the regional database.
For SQLite-backed Durable Objects, we have completely replaced the persistence layer with a new system built from scratch, called Storage Relay Service, or SRS. SRS has already been powering D1 for over a year, and can now be used more directly by applications through Durable Objects.
SRS is based on a simple idea:
Local disk is fast and randomly-accessible, but expensive and prone to disk failures. Object storage (like R2) is cheap and durable, but much slower than local disk and not designed for database-like access patterns. Can we get the best of both worlds by using a local disk as a cache on top of object storage?
So, how does it work?
The mismatch in functionality between local disk and object storage
A SQLite database on disk tends to undergo many small changes in rapid succession. Any row of the database might be updated by any particular query, but the database is designed to avoid rewriting parts that didn’t change. Read queries may randomly access any part of the database. Assuming the right indexes exist to support the query, they should not require reading parts of the database that aren’t relevant to the results, and should complete in microseconds.
Object storage, on the other hand, is designed for an entirely different usage model: you upload an entire “object” (blob of bytes) at a time, and download an entire blob at a time. Each blob has a different name. For maximum efficiency, blobs should be fairly large, from hundreds of kilobytes to gigabytes in size. Latency is relatively high, measured in tens or hundreds of milliseconds.
So how do we back up our SQLite database to object storage? An obviously naive strategy would be to simply make a copy of the database files from time to time and upload it as a new “object”. But, uploading the database on every change — and making the application wait for the upload to complete — would obviously be way too slow. We could choose to upload the database only occasionally — say, every 10 minutes — but this means in the case of a disk failure, we could lose up to 10 minutes of changes. Data loss is, uh, bad! And even then, for most databases, it’s likely that most of the data doesn’t change every 10 minutes, so we’d be uploading the same data over and over again.
Trick one: Upload a log of changes
Instead of uploading the entire database, SRS records a log of changes, and uploads those.
Conveniently, SQLite itself already has a concept of a change log: the Write-Ahead Log, or WAL. SRS always configures SQLite to use WAL mode. In this mode, any changes made to the database are first written to a separate log file. From time to time, the database is “checkpointed”, merging the changes back into the main database file. The WAL format is well-documented and easy to understand: it’s just a sequence of “frames”, where each frame is an instruction to write some bytes to a particular offset in the database file.
SRS monitors changes to the WAL file (by hooking SQLite’s VFS to intercept file writes) to discover the changes being made to the database, and uploads those to object storage.
Unfortunately, SRS cannot simply upload every single change as a separate “object”, as this would result in too many objects, each of which would be inefficiently small. Instead, SRS batches changes over a period of up to 10 seconds, or up to 16 MB worth, whichever happens first, then uploads the whole batch as a single object.
When reconstructing a database from object storage, we must download the series of change batches and replay them in order. Of course, if the database has undergone many changes over a long period of time, this can get expensive. In order to limit how far back it needs to look, SRS also occasionally uploads a snapshot of the entire content of the database. SRS will decide to upload a snapshot any time that the total size of logs since the last snapshot exceeds the size of the database itself. This heuristic implies that the total amount of data that SRS must download to reconstruct a database is limited to no more than twice the size of the database. Since we can delete data from object storage that is older than the latest snapshot, this also means that our total stored data is capped to 2x the database size.
Credit where credit is due: This idea — uploading WAL batches and snapshots to object storage — was inspired by Litestream, although our implementation is different.
Trick two: Relay through other servers in our global network
Batches are only uploaded to object storage every 10 seconds. But obviously, we cannot make the application wait for 10 whole seconds just to confirm a write. So what happens if the application writes some data, returns a success message to the user, and then the machine fails 9 seconds later, losing the data?
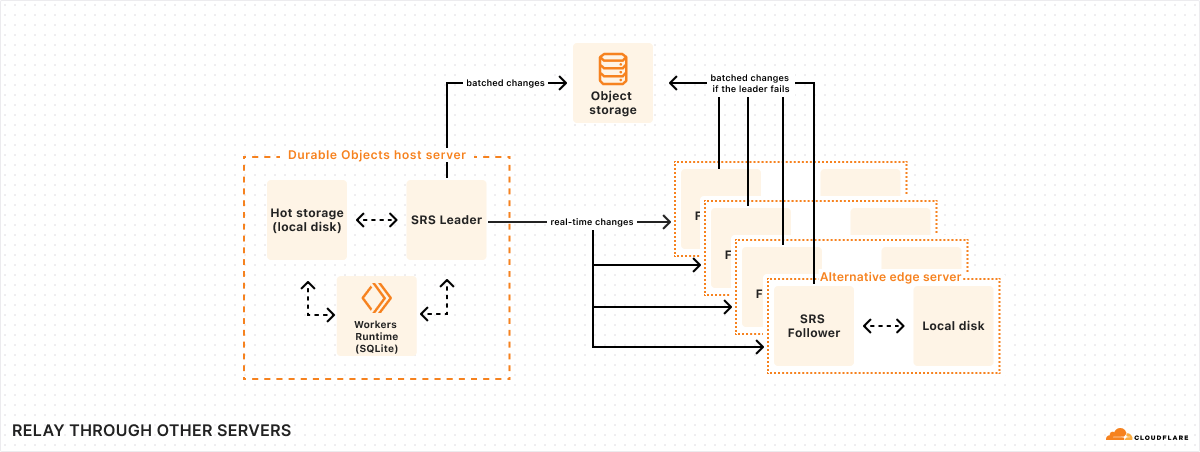
To solve this problem, we take advantage of our global network. Every time SQLite commits a transaction, SRS will immediately forward the change log to five “follower” machines across our network. Once at least three of these followers respond that they have received the change, SRS informs the application that the write is confirmed. (As discussed earlier, the write confirmation opens the Durable Object’s “output gate”, unblocking network communications to the rest of the world.)
When a follower receives a change, it temporarily stores it in a buffer on local disk, and then awaits further instructions. Later on, once SRS has successfully uploaded the change to object storage as part of a batch, it informs each follower that the change has been persisted. At that point, the follower can simply delete the change from its buffer.
However, if the follower never receives the persisted notification, then, after some timeout, the follower itself will upload the change to object storage. Thus, if the machine running the database suddenly fails, as long as at least one follower is still running, it will ensure that all confirmed writes are safely persisted.
Each of a database’s five followers is located in a different physical data center. Cloudflare’s network consists of hundreds of data centers around the world, which means it is always easy for us to find four other data centers nearby any Durable Object (in addition to the one it is running in). In order for a confirmed write to be lost, then, at least four different machines in at least three different physical buildings would have to fail simultaneously (three of the five followers, plus the Durable Object’s host machine). Of course, anything can happen, but this is exceedingly unlikely.
Followers also come in handy when a Durable Object’s host machine is unresponsive. We may not know for sure if the machine has died completely, or if it is still running and responding to some clients but not others. We cannot start up a new instance of the DO until we know for sure that the previous instance is dead – or, at least, that it can no longer confirm writes, since the old and new instances could then confirm contradictory writes. To deal with this situation, if we can’t reach the DO’s host, we can instead try to contact its followers. If we can contact at least three of the five followers, and tell them to stop confirming writes for the unreachable DO instance, then we know that instance is unable to confirm any more writes going forward. We can then safely start up a new instance to replace the unreachable one.
Bonus feature: Point-in-Time Recovery
I mentioned earlier that SQLite-backed Durable Objects can be asked to revert their state to any time in the last 30 days. How does this work?
This was actually an accidental feature that fell out of SRS’s design. Since SRS stores a complete log of changes made to the database, we can restore to any point in time by replaying the change log from the last snapshot. The only thing we have to do is make sure we don’t delete those logs too soon.
Normally, whenever a snapshot is uploaded, all previous logs and snapshots can then be deleted. But instead of deleting them immediately, SRS merely marks them for deletion 30 days later. In the meantime, if a point-in-time recovery is requested, the data is still there to work from.
For a database with a high volume of writes, this may mean we store a lot of data for a lot longer than needed. As it turns out, though, once data has been written at all, keeping it around for an extra month is pretty cheap — typically cheaper, even, than writing it in the first place. It’s a small price to pay for always-on disaster recovery.
Get started with SQLite-in-DO
SQLite-backed DOs are available in beta starting today. You can start building with SQLite-in-DO by visiting developer documentation and provide beta feedback via the #durable-objects channel on our Developer Discord.
Do distributed systems like SRS excite you? Would you like to be part of building them at Cloudflare? We’re hiring!
During Birthday Week 2023, we launched Workers AI. Since then, we have been listening to your feedback, and one thing we’ve heard consistently is that our customers want Workers AI to be faster. In particular, we hear that large language model (LLM) generation needs to be faster. Users want their interactive chat and agents to go faster, developers want faster help, and users do not want to wait for applications and generated website content to load. Today, we’re announcing three upgrades we’ve made to Workers AI to bring faster and more efficient inference to our customers: upgraded hardware, KV cache compression, and speculative decoding.
Thanks to Cloudflare’s 12th generation compute servers, our network now supports a newer generation of GPUs capable of supporting larger models and faster inference. Customers can now use Meta Llama 3.2 11B, Meta’s newly released multi-modal model with vision support, as well as Meta Llama 3.1 70B on Workers AI. Depending on load and time of day, customers can expect to see two to three times the throughput for Llama 3.1 and 3.2 compared to our previous generation Workers AI hardware. More performance information for these models can be found in today’s post: Cloudflare’s Bigger, Better, Faster AI platform.
New KV cache compression methods, now open source
In our effort to deliver low-cost low-latency inference to the world, Workers AI has been developing novel methods to boost efficiency of LLM inference. Today, we’re excited to announce a technique for KV cache compression that can help increase throughput of an inference platform. And we’ve made it open source too, so that everyone can benefit from our research.
It’s all about memory
One of the main bottlenecks when running LLM inference is the amount of vRAM (memory) available. Every word that an LLM processes generates a set of vectors that encode the meaning of that word in the context of any earlier words in the input that are used to generate new tokens in the future. These vectors are stored in the KV cache, causing the memory required for inference to scale linearly with the total number of tokens of all sequences being processed. This makes memory a bottleneck for a lot of transformer-based models. Because of this, the amount of memory an instance has available limits the number of sequences it can generate concurrently, as well as the maximum token length of sequences it can generate.
So what is the KV cache anyway?
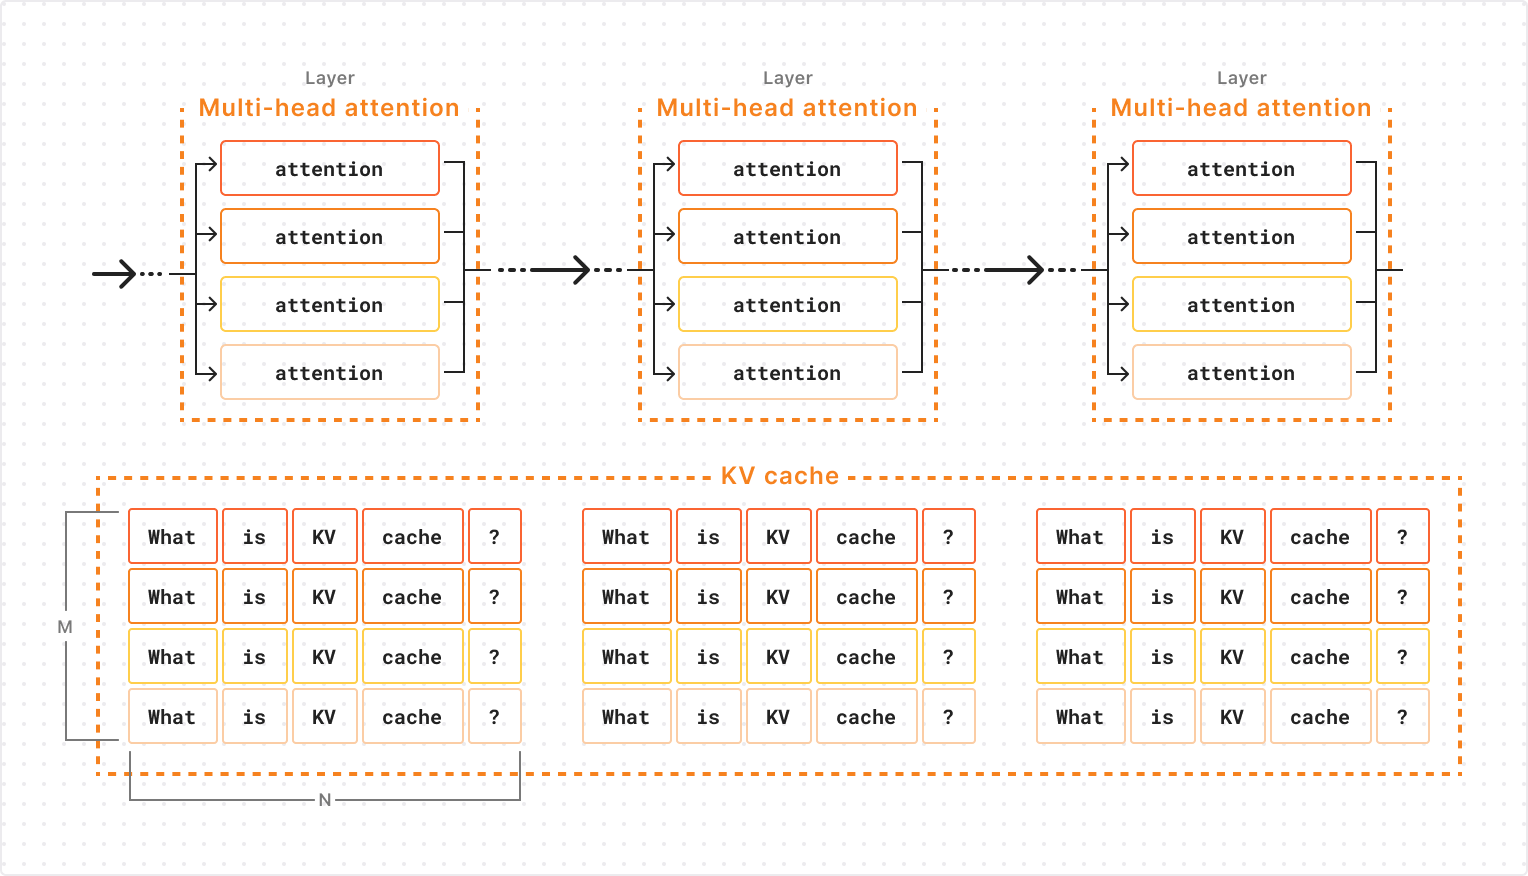
LLMs are made up of layers, with an attention operation occurring in each layer. Within each layer’s attention operation, information is collected from the representations of all previous tokens that are stored in cache. This means that vectors in the KV cache are organized into layers, so that the active layer’s attention operation can only query vectors from the corresponding layer of KV cache. Furthermore, since attention within each layer is parallelized across multiple attention “heads”, the KV cache vectors of a specific layer are further subdivided into groups corresponding to each attention head of that layer.
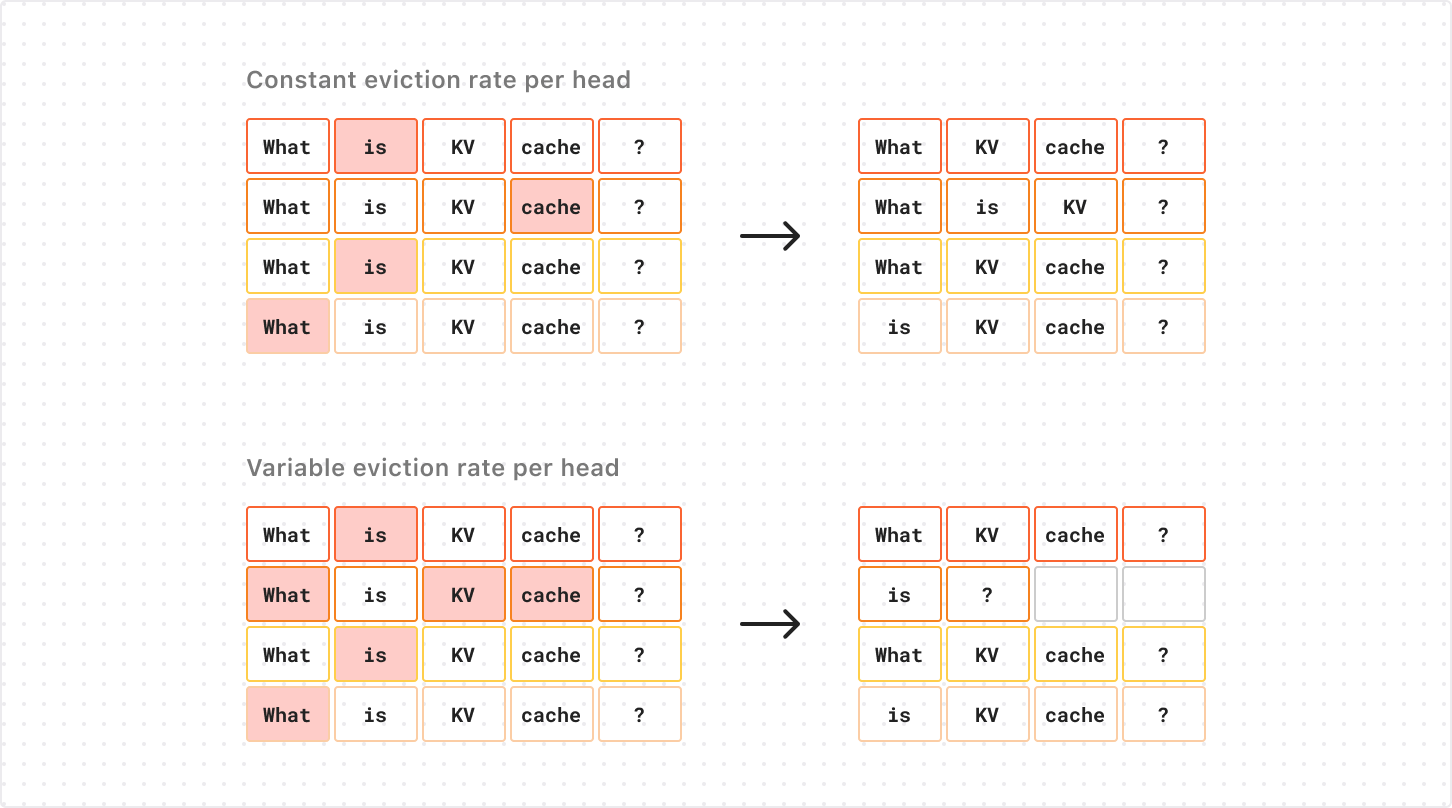
The diagram below shows the structure of an LLM’s KV cache for a single sequence being generated. Each cell represents a KV and the model’s representation for a token consists of all KV vectors for that token across all attention heads and layers. As you can see, the KV cache for a single layer is allocated as an M x N matrix of KV vectors where M is the number of attention heads and N is the sequence length. This will be important later!
Now that we know what the KV cache looks like, let’s dive into how we can shrink it!
The most common approach to compressing the KV cache involves identifying vectors within it that are unlikely to be queried by future attention operations and can therefore be removed without impacting the model’s outputs. This is commonly done by looking at the past attention weights for each pair of key and value vectors (a measure of the degree with which that KV’s representation has been queried during past attention operations) and selecting the KVs that have received the lowest total attention for eviction. This approach is conceptually similar to a LFU (least frequently used) cache management policy: the less a particular vector is queried, the more likely it is to be evicted in the future.
Different attention heads need different compression rates
As we saw earlier, the KV cache for each sequence in a particular layer is allocated on the GPU as a # attention heads X sequence length tensor. This means that the total memory allocation scales with the maximum sequence length for all attention heads of the KV cache. Usually this is not a problem, since each sequence generates the same number of KVs per attention head.
When we consider the problem of eviction-based KV cache compression, however, this forces us to remove an equal number of KVs from each attention head when doing the compression. If we remove more KVs from one attention head alone, those removed KVs won’t actually contribute to lowering the memory footprint of the KV cache on GPU, but will just add more empty “padding” to the corresponding rows of the tensor. You can see this in the diagram below (note the empty cells in the second row below):
The extra compression along the second head frees slots for two KVs, but the cache’s shape (and memory footprint) remains the same.
This forces us to use a fixed compression rate for all attention heads of KV cache, which is very limiting on the compression rates we can achieve before compromising performance.
Enter PagedAttention
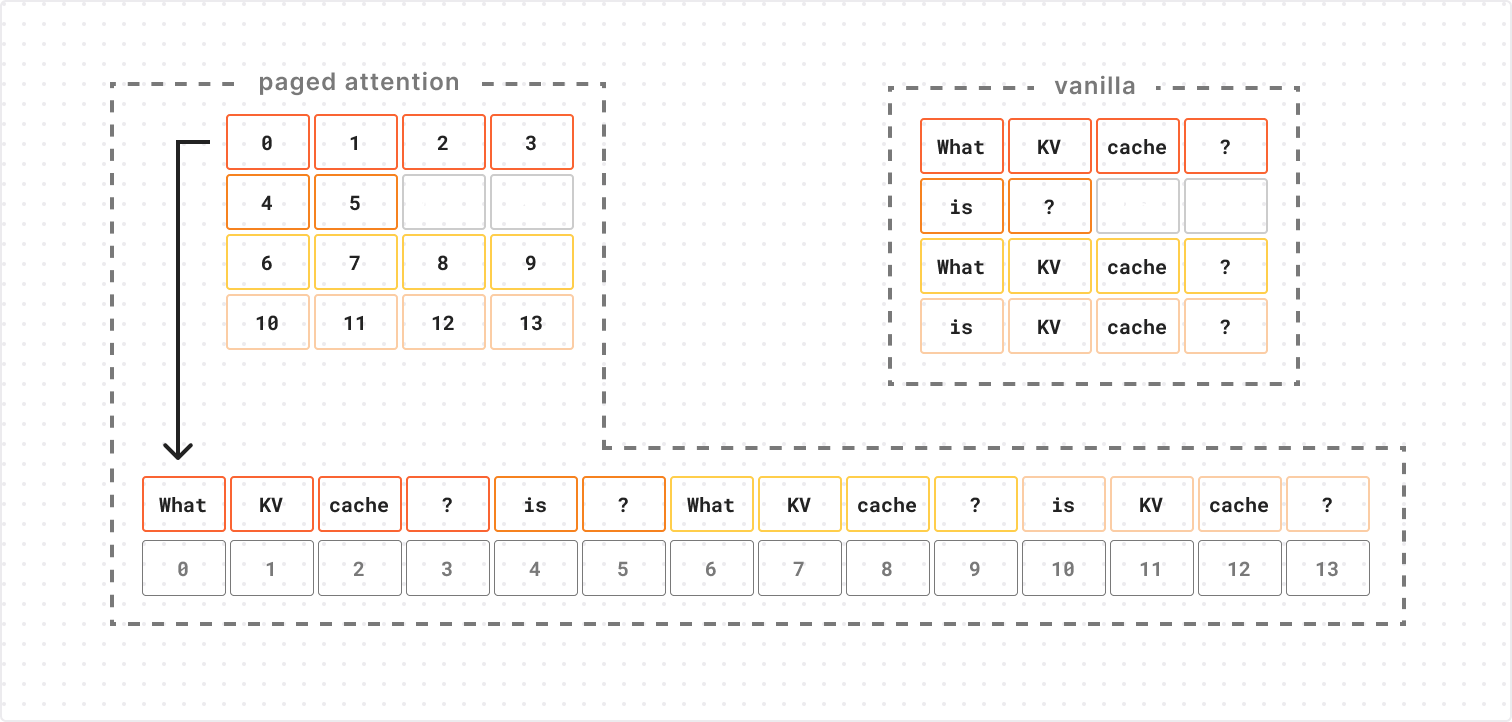
The solution to this problem is to change how our KV cache is represented in physical memory. PagedAttention can represent N x M tensors with padding efficiently by using an N x M block table to index into a series of “blocks”.
This lets us retrieve the ith element of a row by taking the ith block number from that row in the block table and using the block number to lookup the corresponding block, so we avoid allocating space to padding elements in our physical memory representation. In our case, the elements in physical memory are the KV cache vectors, and the M and N that define the shape of our block table are the number of attention heads and sequence length, respectively. Since the block table is only storing integer indices (rather than high-dimensional KV vectors), its memory footprint is negligible in most cases.
Results
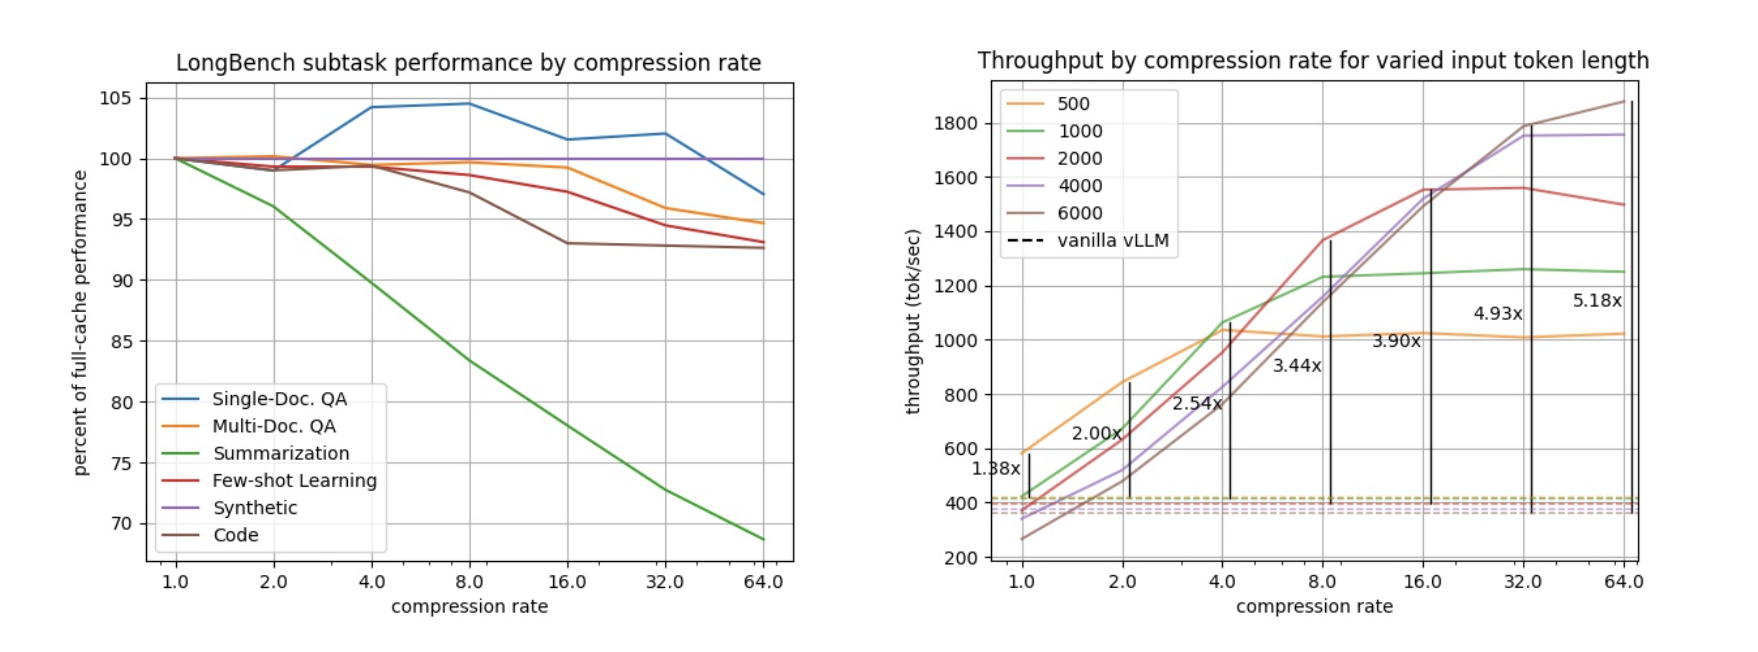
Using paged attention lets us apply different rates of compression to different heads in our KV cache, giving our compression strategy more flexibility than other methods. We tested our compression algorithm on LongBench (a collection of long-context LLM benchmarks) with Llama-3.1-8B and found that for most tasks we can retain over 95% task performance while reducing cache size by up to 8x (left figure below). Over 90% task performance can be retained while further compressing up to 64x. That means you have room in memory for 64 times as many tokens!
This lets us increase the number of requests we can process in parallel, increasing the total throughput (total tokens generated per second) by 3.44x and 5.18x for compression rates of 8x and 64x, respectively (right figure above).
Try it yourself!
If you’re interested in taking a deeper dive check out our vLLM fork and get compressing!!
Speculative decoding for faster throughput
A new inference strategy that we implemented is speculative decoding, which is a very popular way to get faster throughput (measured in tokens per second). LLMs work by predicting the next expected token (a token can be a word, word fragment or single character) in the sequence with each call to the model, based on everything that the model has seen before. For the first token generated, this means just the initial prompt, but after that each subsequent token is generated based on the prompt plus all other tokens that have been generated. Typically, this happens one token at a time, generating a single word, or even a single letter, depending on what comes next.
But what about this prompt:
Knock, knock!
If you are familiar with knock-knock jokes, you could very accurately predict more than one token ahead. For an English language speaker, what comes next is a very specific sequence that is four to five tokens long: “Who’s there?” or “Who is there?” Human language is full of these types of phrases where the next word has only one, or a few, high probability choices. Idioms, common expressions, and even basic grammar are all examples of this. So for each prediction the model makes, we can take it a step further with speculative decoding to predict the next n tokens. This allows us to speed up inference, as we’re not limited to predicting one token at a time.
There are several different implementations of speculative decoding, but each in some way uses a smaller, faster-to-run model to generate more than one token at a time. For Workers AI, we have applied prompt-lookup decoding to some of the LLMs we offer. This simple method matches the last n tokens of generated text against text in the prompt/output and predicts candidate tokens that continue these identified patterns as candidates for continuing the output. In the case of knock-knock jokes, it can predict all the tokens for “Who’s there” at once after seeing “Knock, knock!”, as long as this setup occurs somewhere in the prompt or previous dialogue already. Once these candidate tokens have been predicted, the model can verify them all with a single forward-pass and choose to either accept or reject them. This increases the generation speed of llama-3.1-8b-instruct by up to 40% and the 70B model by up to 70%.
Speculative decoding has tradeoffs, however. Typically, the results of a model using speculative decoding have a lower quality, both when measured using benchmarks like MMLU as well as when compared by humans. More aggressive speculation can speed up sequence generation, but generally comes with a greater impact to the quality of the result. Prompt lookup decoding offers one of the smallest overall quality impacts while still providing performance improvements, and we will be adding it to some language models on Workers AI including @cf/meta/llama-3.1-8b-instruct.
And, by the way, here is one of our favorite knock-knock jokes, can you guess the punchline?
Knock, knock!
Who’s there?
Figs!
Figs who?
Figs the doorbell, it’s broken!
Keep accelerating
As the AI industry continues to evolve, there will be new hardware and software that allows customers to get faster inference responses. Workers AI is committed to researching, implementing, and making upgrades to our services to help you get fast inference. As an Inference-as-a-Service platform, you’ll be able to benefit from all the optimizations we apply, without having to hire your own team of ML researchers and SREs to manage inference software and hardware deployments.
We’re excited for you to try out some of these new releases we have and let us know what you think! Check out our full-suite of AI announcements here and check out the developer docs to get started.
Today, we’re pleased to offer startups up to $250,000 in credits to use on Cloudflare’s Developer Platform. This new credits system will allow you to clearly see usage and associated fees to plan for a predictable future after the $250,000 in credits have been used up or after one year, whichever happens first.
You can see eligibility criteria and apply to the start-up program here.
What can you use the credits for?
Credits can be applied to all Developer Platform products, as well as Argo and Cache Reserve. Moreover, we provide participants with up to three Enterprise-level domains, which includes CDN, DDoS, DNS, WAF, Zero Trust, and other security and performance products that a participant can enable for their website.
Developer tools and building on Cloudflare
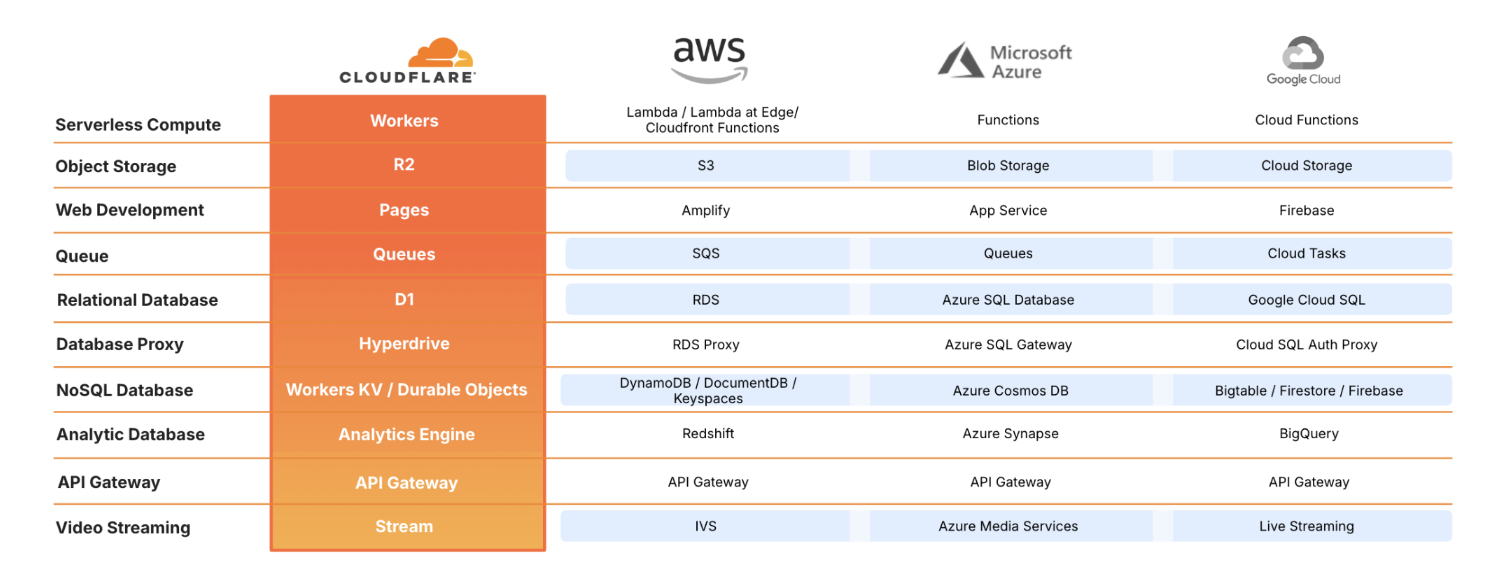
You can use credits for Cloudflare Developer Platform products, including those listed in the table below.
Note: credits for the Cloudflare Startup Program apply to Cloudflare products only, this table is illustrative of similar products in the market.
Speed and performance with Cloudflare
We know that founders need all the help they can get when starting their businesses. Beyond the Developer Platform, you can also use the Startup Program for our speed and performance products. Getting customers where they need to go within milliseconds on your website or application is the difference between closing a sale or not. You can test your speed here and learn how to optimize your speed and performance here with solutions like: Images, Argo, and Early Hints.
Security from Cloudflare
But, wait, there’s more: beyond the Developer Platform products and speed tools, you can also use Cloudflare’s many security features through the Startup Program as well. These include Web Application Firewall (WAF), DDoS Alerts, bundled protection plans, and more. The Startup Program also includes Zero Trust solutions. Learn how others are securing their technology and tools with Cloudflare Zero Trust.
For more inspiration, check out our Built with Cloudflare site, which highlights what other startups are building.
Who can use the credits?
Eligibility criteria can be found here and include:
Companies building a software-based product or service
Founded within the last 5 years (2019-2024)
Have between $50,000 - $5,000,000 in funding
Note that for startups who have not yet raised at least $50,000, there may be other opportunities for lower credit amounts. Please apply with the promo code “BOOTSTRAPPED” if you haven’t raised $50,000 yet, but are interested in the Cloudflare Startup Program
Have a LinkedIn profile, valid website, and email address
Bonus criteria that adds to your application: being part of an approved accelerator
What will you build?
We’re excited to see what you will build. Please share what you’re up to with us so that we can help you however it makes sense. If you’re actively using Cloudflare’s Developer Platform, we’d love to hear more about what you’re building and share it on our Built with Cloudflare site.
Are you a startup looking for additional support, resources, or access to funding? Apply for our Workers Launchpad Program! The program runs for a few months, and in addition to the Startup Program, participants get access to hands-on bootcamp sessions, Solutions Architect office hours, introductions to VCs, and the opportunity to present at Demo Day.
Why does Cloudflare support founders and startups?
Founders and developers face enough challenges without having to worry about incurring egregious costs to test technology and start building in the earliest days. You have the world at your fingertips and should be empowered to build and create without limitations. Invest money in your innovation, not in the infrastructure and technology that supports it.
The Startup Program understands this founder experience deeply, as the team is made up of former founders. Cloudflare is committed to programs like this to empower founders building the next big thing. Offering up to $250,000 in credits will allow folks to leverage even more of what we have to offer: a developer experience that removes friction, saves money, and gets applications spun up in hours, not days.
We want to support founders from everywhere on earth.
Hyperdrive (Cloudflare’s globally distributed SQL connection pooler and cache) recently added support for Postgres protocol-level named prepared statements across pooled connections. Named prepared statements allow Postgres to cache query execution plans, providing potentially substantial performance improvements. Further, many popular drivers in the ecosystem use these by default, meaning that not having them is a bit of a footgun for developers. We are very excited that Hyperdrive’s users will now have access to better performance and a more seamless development experience, without needing to make any significant changes to their applications!
While we’re not the first connection pooler to add this support (PgBouncer got to it in October 2023 in version 1.21, for example), there were some unique challenges in how we implemented it. To that end, we wanted to do a deep dive on what it took for us to deliver this.
Hyper-what?
One of the classic problems of building on the web is that your users are everywhere, but your database tends to be in one spot. Combine that with pesky limitations like network routing, or the speed of light, and you can often run into situations where your users feel the pain of having your database so far away. This can look like slower queries, slower startup times, and connection exhaustion as everything takes longer to accomplish.
Hyperdrive is designed to make the centralized databases you already have feel like they’re global. We use our global network to get faster routes to your database, keep connection pools primed, and cache your most frequently run queries as close to users as possible.
Postgres Message Protocol
To understand exactly what the challenge with prepared statements is, it’s first necessary to dig in a bit to the Postgres Message Protocol. Specifically, we are going to take a look at the protocol for an “extended” query, which uses different message types and is a bit more complex than a “simple” query, but which is more powerful and thus more widely used.
A query using Hyperdrive might be coded something like this, but a lot goes on under the hood in order for Postgres to reliably return your response.
import postgres from "postgres";

// with Hyperdrive, we don't have to disable prepared statements anymore!
// const sql = postgres(env.HYPERDRIVE.connectionString, {prepare: false});

// make a connection, with the default postgres.js settings (prepare is set to true)
const sql = postgres(env.HYPERDRIVE.connectionString);

// This sends the query, and while it looks like a single action it contains several
// messages implied within it
let [{ a, b, c, id }] = await sql`SELECT a, b, c, id FROM hyper_test WHERE id = ${target_id}`;
To prepare a statement, a Postgres client begins by sending a Parse message. This includes the query string, the number of parameters to be interpolated, and the statement’s name. The name is a key piece of this puzzle. If it is empty, then Postgres uses a special “unnamed” prepared statement slot that gets overwritten on each new Parse. These are relatively easy to support, as most drivers will keep the entirety of a message sequence for unnamed statements together, and will not try to get too aggressive about reusing the prepared statement because it is overwritten so often.
If the statement has a name, however, then it is kept prepared for the remainder of the Postgres session (unless it is explicitly removed with DEALLOCATE). This is convenient because parsing a query string and preparing the statement costs bytes sent on the wire and CPU cycles to process, so reusing a statement is quite a nice optimization.
Once done with Parse, there are a few remaining steps to (the simplest form of) an extended query:
A Bind message, which provides the specific values to be passed for the parameters in the statement (if any).
An Execute message, which tells the Postgres server to actually perform the data retrieval and processing.
And finally a Sync message, which causes the server to close the implicit transaction, return results, and provides a synchronization point for error handling.
While that is the core pattern for accomplishing an extended protocol query, there are many more complexities possible (named Portal, ErrorResponse, etc.).
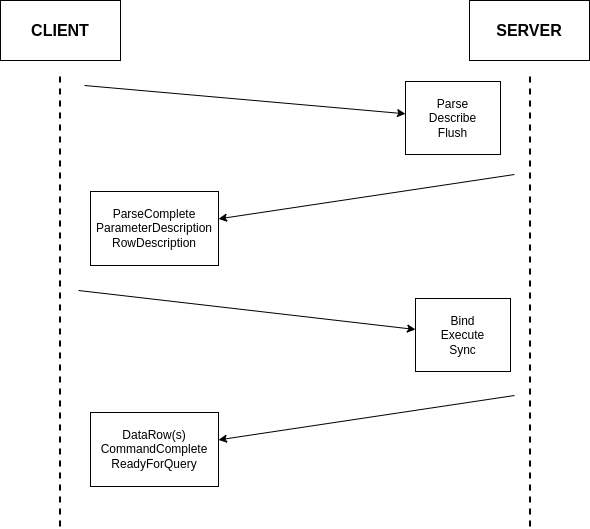
We will briefly mention one other complexity we often encounter in this protocol, which is Describe messages. Many drivers leverage Postgres’ built-in types to help with deserialization of the results into structs or classes. This is accomplished by sending a Parse-Describe-Flush/Sync sequence, which will send a statement to be prepared, and will expect back information about the types and data the query will return. This complicates bookkeeping around named prepared statements, as now there are two separate queries, with two separate kinds of responses, that must be kept track of. We won’t go into much depth on the tradeoffs of an additional round-trip in exchange for advanced information about the results’ format, but suffice it to say that it must be handled explicitly in order for the overall system to gracefully support prepared statements.
So the basic query from our code above looks like this from a message perspective:
The first challenge that Hyperdrive must solve (that many other connection poolers don’t have) is that it’s also a cache.
The happiest path for a query on Hyperdrive never travels far, and we are quite proud of the low latency of our cache hits. However, this presents a particular challenge in the case of an extended protocol query. A Parse by itself is insufficient as a cache key, both because the parameter values in the Bind messages can alter the expected results, and because it might be followed up with either a Describe or an Execute message which will invoke drastically different responses.
So Hyperdrive cannot simply pass each message to the origin database, as we must buffer them in a message log until we have enough information to reliably distinguish between cache keys. It turns out that receiving a Sync is quite a natural point at which to check whether you have enough information to serve a response. For most scenarios, we buffer until we receive a Sync, and then (assuming the scenario is cacheable) we determine whether we can serve the response from cache or we need to take a connection to the origin database.
Taking a Connection From the Pool
Assuming we aren’t serving a response from cache, for whatever reason, we’ll need to take an origin connection from our pool. One of the key advantages any connection pooler offers is in allowing many client connections to share few database connections, so minimizing how often and for how long these connections are held is crucial to making Hyperdrive performant.
To this end, Hyperdrive operates in what is traditionally called “transaction mode”. This means that a connection taken from the pool for any given transaction is returned once that transaction concludes. This is in contrast to what is often called “session mode”, where once a connection is taken from the pool it is held by the client until the client disconnects.
For Hyperdrive, allowing any client to take any database connection is vital. This is because if we “pin” a client to a given database connection then we have one fewer available for every other possible client. You can run yourself out of database connections very quickly once you start down that path, especially when your clients are many small Workers spread around the world.
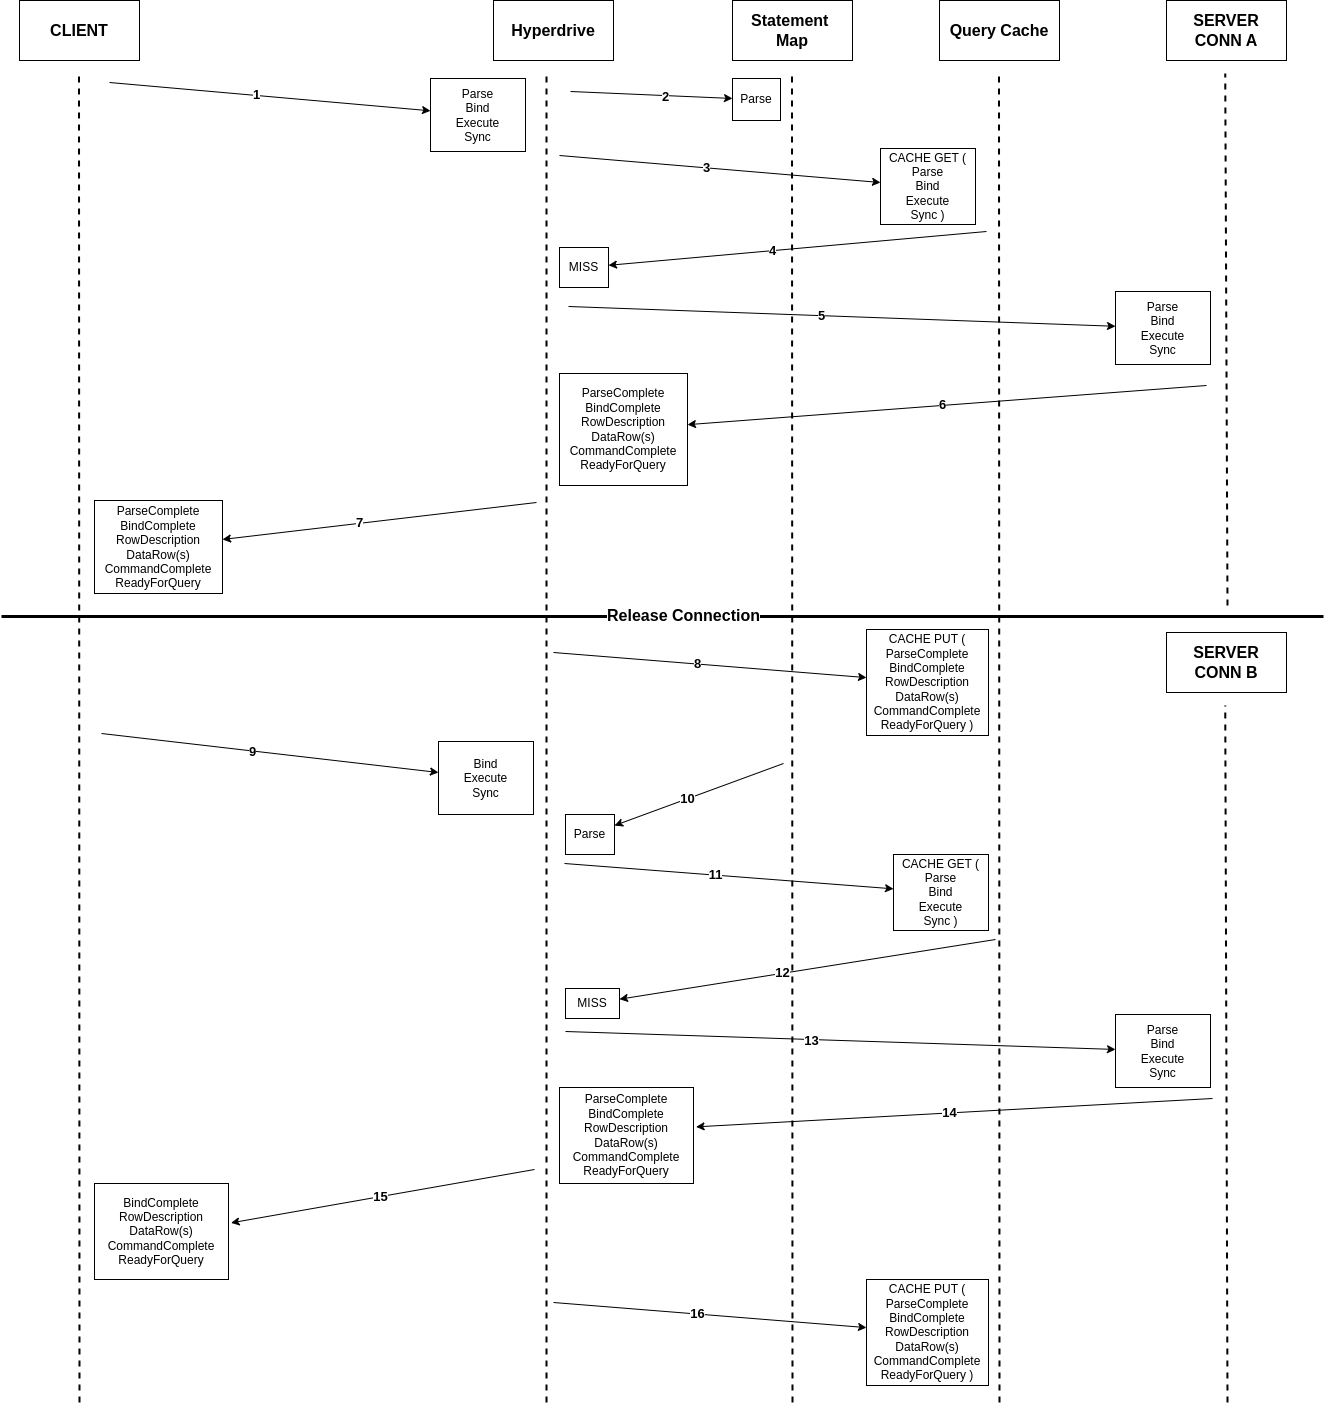
The challenge prepared statements present to this scenario is that they exist at the “session” scope, which is to say, at the scope of one connection. If a client prepares a statement on connection A, but tries to reuse it and gets assigned connection B, Postgres will naturally throw an error claiming the statement doesn’t exist in the given session. No results will be returned, the client is unhappy, and all that’s left is to retry with a Parse message included. This causes extra round-trips between client and server, defeating the whole purpose of what is meant to be an optimization.
One of the goals of a connection pooler is to be as transparent to the client and server as possible. There are limitations, as Postgres will let you do some powerful things to session state that cannot be reasonably shared across arbitrary client connections, but to the extent possible the endpoints should not have to know or care about any multiplexing happening between them.
This means that when a client sends a Parse message on its connection, it should expect that the statement will be available for reuse when it wants to send a Bind-Execute-Sync sequence later on. It also means that the server should not get Bind messages for statements that only exist on some other session. Maintaining this illusion is the crux of providing support for this feature.
Putting it all together
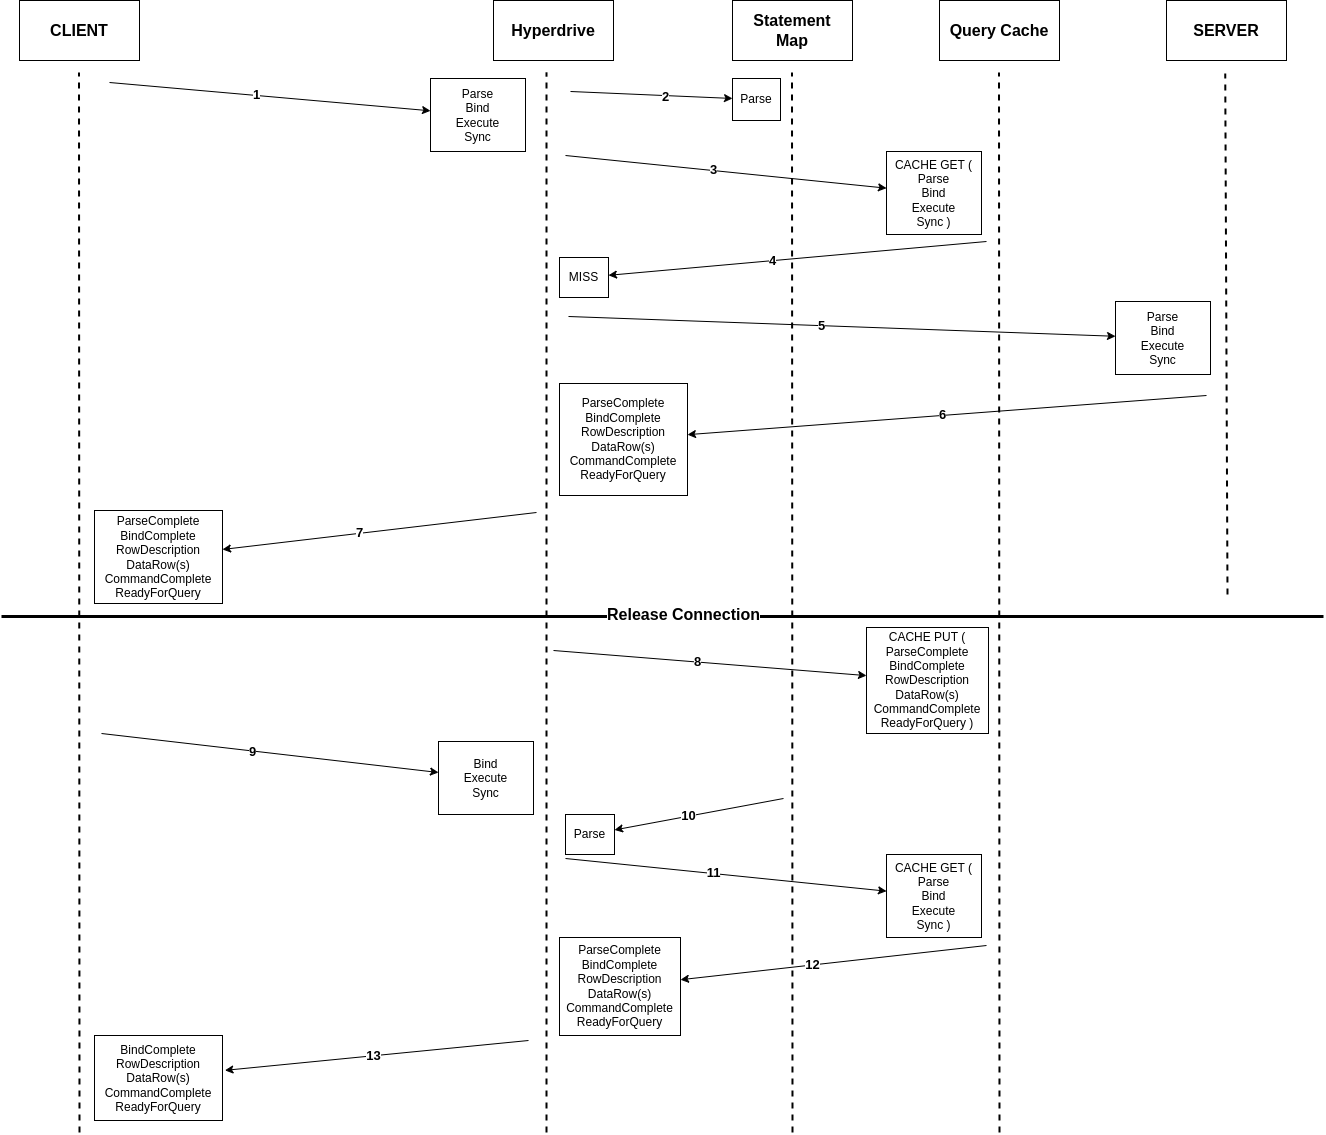
So, what does the solution look like? If a client sends Parse-Bind-Execute-Sync with a named prepared statement, then later sends Bind-Execute-Sync to reuse it, how can we make sure that everything happens as expected? The solution, it turns out, needs just a few built-in Rust data structures for efficiently capturing what we need (a HashMap, some LruCaches and a VecDeque), and some straightforward business logic to keep track of when to intervene in the messages being passed back and forth.
Whenever a named Parse comes in, we store it in an in-memory HashMap on the server that handles message processing for that client’s connection. This persists until the client is disconnected. This means that whenever we see anything referencing the statement, we can go retrieve the complete message defining it. We’ll come back to this in a moment.
Once we’ve buffered all the messages we can and gotten to the point where it’s time to return results (let’s say because the client sent a Sync), we need to start applying some logic. For the sake of brevity we’re going to omit talking through error handling here, as it does add some significant complexity but is somewhat out of scope for this discussion.
There are two main questions that determine how we should proceed:
Does our message sequence include a Parse, or are we trying to reuse a pre-existing statement?
Do we have a cache hit or are we serving from the origin database?
This gives us four scenarios to consider:
Parse with cache hit
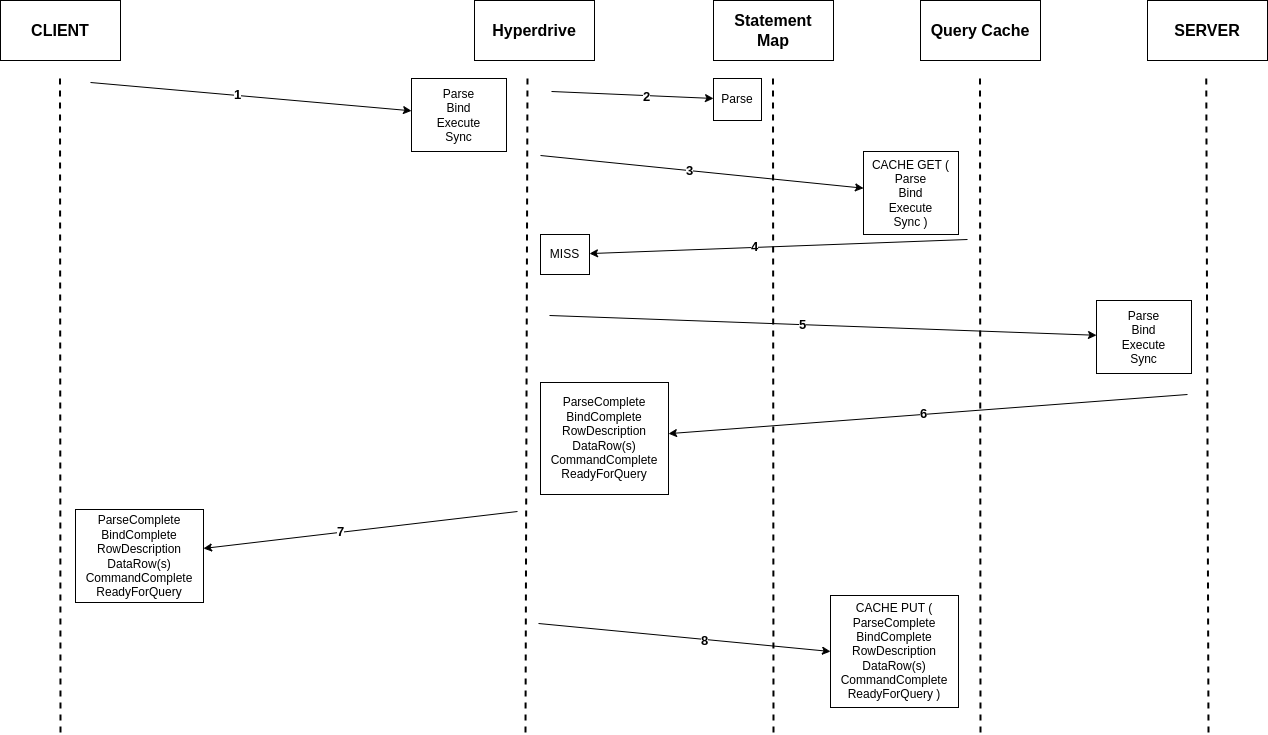
Parse with cache miss
Reuse with cache hit
Reuse with cache miss
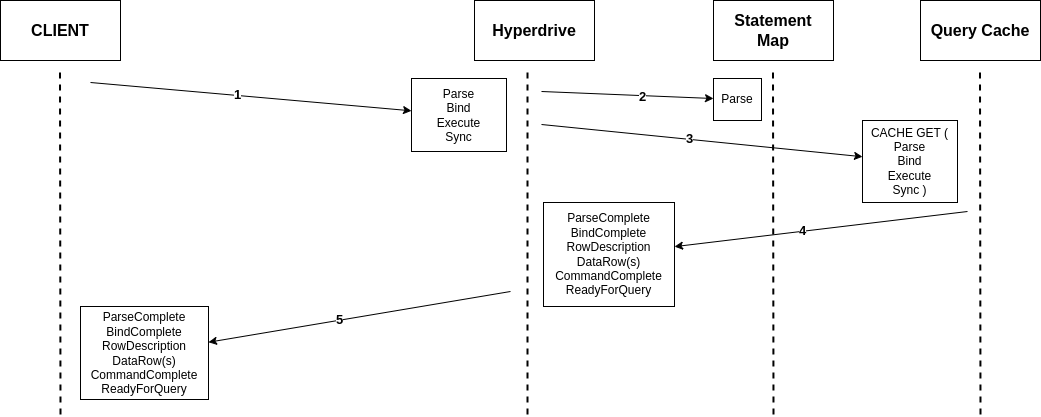
A Parse with a cache hit is the easiest path to address, as we don’t need to do anything special. We use the messages sent as a cache key, and serve the results back to the client. We will still keep the Parse in our HashMap in case we want it later (#2 below), but otherwise we’re good to go.
A Parse with a cache miss is a bit more complicated, as now we need to send these messages to the origin server. We take a connection at random from our pool and do so, passing the results back to the client. With that, we’ve begun to make changes to session state such that all our database connections are no longer identical to each other. To keep track of what we’ve done to muddy up our state, we keep a LruCache on each connection of which statements it already has prepared. In the case where we need to evict from such a cache, we will also DEALLOCATE the statement on the connection to keep things tracked correctly.
Reuse with a cache hit is yet more tricky, but still straightforward enough. In the example below, we are sent a Bind with the same parameters twice (#1 and #9). We must identify that we received a Bind without a preceding Parse, we must go retrieve that Parse (#10), and we must use the information from it to build our cache key. Once all that is accomplished, we can serve our results from cache, needing only to trim out the ParseComplete within the cached results before returning them to the client.
Reuse with a cache miss is the hardest scenario, as it may require us to lie in both directions. In the example below, we cache results for one set of parameters (#8), but are sent a Bind with different parameters (#9). As in the cache hit scenario, we must identify that we were not sent a Parse as part of the current message sequence, retrieve it from our HashMap (#10), and build our cache key to GET from cache and confirm the miss (#11). Once we take a connection from the pool, though, we then need to check if it already has the statement we want prepared. If not, we must take our saved Parse and prepend it to our message log to be sent along to the origin database (#13). Thus, what the server receives looks like a perfectly valid Parse-Bind-Execute-Sync sequence. This is where our VecDeque (mentioned above) comes in, as converting our message log to that structure allowed us to very ergonomically make such changes without needing to rebuild the whole byte sequence. Once we receive the response from the server, all that’s needed is to trim out the initial ParseComplete response from the server, as a well-made client would likely be very confused receiving such a response to a Parse it didn’t send. With that message trimmed out, however, the client is in the position of getting exactly what it asked for, and both sides of the conversation are happy.
Dénouement
Now that we’ve got a working solution, where all parties are functioning well, let’s review! Our solution lets us share database connections across arbitrary clients with no “pinning”, no custom handling on either client or server, and supports reuse of prepared statements to reduce CPU load on re-parsing queries and reduce network traffic on re-sending Parse messages. Engineering always involves tradeoffs, so the cost of this is that we will sometimes still need to sneak in a Parse because a client got assigned a different connection on reuse, and in those scenarios there is a small amount of additional memory overhead because the same statement is prepared on multiple connections.
Cloudforce One is publishing the results of our investigation and real-time effort to detect, deny, degrade, disrupt, and delay threat activity by the Russia-aligned threat actor FlyingYeti during their latest phishing campaign targeting Ukraine. At the onset of Russia’s invasion of Ukraine on February 24, 2022, Ukraine introduced a moratorium on evictions and termination of utility services for unpaid debt. The moratorium ended in January 2024, resulting in significant debt liability and increased financial stress for Ukrainian citizens. The FlyingYeti campaign capitalized on anxiety over the potential loss of access to housing and utilities by enticing targets to open malicious files via debt-themed lures. If opened, the files would result in infection with the PowerShell malware known as COOKBOX, allowing FlyingYeti to support follow-on objectives, such as installation of additional payloads and control over the victim’s system.
Since April 26, 2024, Cloudforce One has taken measures to prevent FlyingYeti from launching their phishing campaign – a campaign involving the use of Cloudflare Workers and GitHub, as well as exploitation of the WinRAR vulnerability CVE-2023-38831. Our countermeasures included internal actions, such as detections and code takedowns, as well as external collaboration with third parties to remove the actor’s cloud-hosted malware. Our effectiveness against this actor prolonged their operational timeline from days to weeks. For example, in a single instance, FlyingYeti spent almost eight hours debugging their code as a result of our mitigations. By employing proactive defense measures, we successfully stopped this determined threat actor from achieving their objectives.
Executive Summary
On April 18, 2024, Cloudforce One detected the Russia-aligned threat actor FlyingYeti preparing to launch a phishing espionage campaign targeting individuals in Ukraine.
From mid-April to mid-May, we observed FlyingYeti conduct reconnaissance activity, create lure content for use in their phishing campaign, and develop various iterations of their malware. We assessed that the threat actor intended to launch their campaign in early May, likely following Orthodox Easter.
After several weeks of monitoring actor reconnaissance and weaponization activity (Cyber Kill Chain Stages 1 and 2), we successfully disrupted FlyingYeti’s operation moments after the final COOKBOX payload was built.
The payload included an exploit for the WinRAR vulnerability CVE-2023-38831, which FlyingYeti will likely continue to use in their phishing campaigns to infect targets with malware.
We offer steps users can take to defend themselves against FlyingYeti phishing operations, and also provide recommendations, detections, and indicators of compromise.
Who is FlyingYeti?
FlyingYeti is the cryptonym given by Cloudforce One to the threat group behind this phishing campaign, which overlaps with UAC-0149 activity tracked by CERT-UA in February and April 2024. The threat actor uses dynamic DNS (DDNS) for their infrastructure and leverages cloud-based platforms for hosting malicious content and for malware command and control (C2). Our investigation of FlyingYeti TTPs suggests this is likely a Russia-aligned threat group. The actor appears to primarily focus on targeting Ukrainian military entities. Additionally, we observed Russian-language comments in FlyingYeti’s code, and the actor’s operational hours falling within the UTC+3 time zone.
Campaign background
In the days leading up to the start of the campaign, Cloudforce One observed FlyingYeti conducting reconnaissance on payment processes for Ukrainian communal housing and utility services:
April 22, 2024 – research into changes made in 2016 that introduced the use of QR codes in payment notices
April 22, 2024 – research on current developments concerning housing and utility debt in Ukraine
April 25, 2024 – research on the legal basis for restructuring housing debt in Ukraine as well as debt involving utilities, such as gas and electricity
Cloudforce One judges that the observed reconnaissance is likely due to the Ukrainian government’s payment moratorium introduced at the start of the full-fledged invasion in February 2022. Under this moratorium, outstanding debt would not lead to evictions or termination of provision of utility services. However, on January 9, 2024, the government lifted this ban, resulting in increased pressure on Ukrainian citizens with outstanding debt. FlyingYeti sought to capitalize on that pressure, leveraging debt restructuring and payment-related lures in an attempt to increase their chances of successfully targeting Ukrainian individuals.
Analysis of the Komunalka-themed phishing site
The disrupted phishing campaign would have directed FlyingYeti targets to an actor-controlled GitHub page at hxxps[:]//komunalka[.]github[.]io, which is a spoofed version of the Kyiv Komunalka communal housing site https://www.komunalka.ua. Komunalka functions as a payment processor for residents in the Kyiv region and allows for payment of utilities, such as gas, electricity, telephone, and Internet. Additionally, users can pay other fees and fines, and even donate to Ukraine’s defense forces.
Based on past FlyingYeti operations, targets may be directed to the actor’s Github page via a link in a phishing email or an encrypted Signal message. If a target accesses the spoofed Komunalka platform at hxxps[:]//komunalka[.]github[.]io, the page displays a large green button with a prompt to download the document “Рахунок.docx” (“Invoice.docx”), as shown in Figure 1. This button masquerades as a link to an overdue payment invoice but actually results in the download of the malicious archive “Заборгованість по ЖКП.rar” (“Debt for housing and utility services.rar”).
Figure 1: Prompt to download malicious archive “Заборгованість по ЖКП.rar”
A series of steps must take place for the download to successfully occur:
The target clicks the green button on the actor’s GitHub page hxxps[:]//komunalka.github[.]io
The target’s device sends an HTTP POST request to the Cloudflare Worker worker-polished-union-f396[.]vqu89698[.]workers[.]dev with the HTTP request body set to “user=Iahhdr”
The Cloudflare Worker processes the request and evaluates the HTTP request body
If the request conditions are met, the Worker fetches the RAR file from hxxps[:]//raw[.]githubusercontent[.]com/kudoc8989/project/main/Заборгованість по ЖКП.rar, which is then downloaded on the target’s device
Cloudforce One identified the infrastructure responsible for facilitating the download of the malicious RAR file and remediated the actor-associated Worker, preventing FlyingYeti from delivering its malicious tooling. In an effort to circumvent Cloudforce One’s mitigation measures, FlyingYeti later changed their malware delivery method. Instead of the Workers domain fetching the malicious RAR file, it was loaded directly from GitHub.
Analysis of the malicious RAR file
During remediation, Cloudforce One recovered the RAR file “Заборгованість по ЖКП.rar” and performed analysis of the malicious payload. The downloaded RAR archive contains multiple files, including a file with a name that contains the unicode character “U+201F”. This character appears as whitespace on Windows devices and can be used to “hide” file extensions by adding excessive whitespace between the filename and the file extension. As highlighted in blue in Figure 2, this cleverly named file within the RAR archive appears to be a PDF document but is actually a malicious CMD file (“Рахунок на оплату.pdf[unicode character U+201F].cmd”).
Figure 2: Files contained in the malicious RAR archive “Заборгованість по ЖКП.rar” (“Housing Debt.rar”)
FlyingYeti included a benign PDF in the archive with the same name as the CMD file but without the unicode character, “Рахунок на оплату.pdf” (“Invoice for payment.pdf”). Additionally, the directory name for the archive once decompressed also contained the name “Рахунок на оплату.pdf”. This overlap in names of the benign PDF and the directory allows the actor to exploit the WinRAR vulnerability CVE-2023-38831. More specifically, when an archive includes a benign file with the same name as the directory, the entire contents of the directory are opened by the WinRAR application, resulting in the execution of the malicious CMD. In other words, when the target believes they are opening the benign PDF “Рахунок на оплату.pdf”, the malicious CMD file is executed.
The CMD file contains the FlyingYeti PowerShell malware known as COOKBOX. The malware is designed to persist on a host, serving as a foothold in the infected device. Once installed, this variant of COOKBOX will make requests to the DDNS domain postdock[.]serveftp[.]com for C2, awaiting PowerShell cmdlets that the malware will subsequently run.
Alongside COOKBOX, several decoy documents are opened, which contain hidden tracking links using the Canary Tokens service. The first document, shown in Figure 3 below, poses as an agreement under which debt for housing and utility services will be restructured.
Figure 3: Decoy document Реструктуризація боргу за житлово комунальні послуги.docx
The second document (Figure 4) is a user agreement outlining the terms and conditions for the usage of the payment platform komunalka[.]ua.
The use of relevant decoy documents as part of the phishing and delivery activity are likely an effort by FlyingYeti operators to increase the appearance of legitimacy of their activities.
The phishing theme we identified in this campaign is likely one of many themes leveraged by this actor in a larger operation to target Ukrainian entities, in particular their defense forces. In fact, the threat activity we detailed in this blog uses many of the same techniques outlined in a recent FlyingYeti campaign disclosed by CERT-UA in mid-April 2024, where the actor leveraged United Nations-themed lures involving Peace Support Operations to target Ukraine’s military. Due to Cloudforce One’s defensive actions covered in the next section, this latest FlyingYeti campaign was prevented as of the time of publication.
Mitigating FlyingYeti activity
Cloudforce One mitigated FlyingYeti’s campaign through a series of actions. Each action was taken to increase the actor’s cost of continuing their operations. When assessing which action to take and why, we carefully weighed the pros and cons in order to provide an effective active defense strategy against this actor. Our general goal was to increase the amount of time the threat actor spent trying to develop and weaponize their campaign.
We were able to successfully extend the timeline of the threat actor’s operations from hours to weeks. At each interdiction point, we assessed the impact of our mitigation to ensure the actor would spend more time attempting to launch their campaign. Our mitigation measures disrupted the actor’s activity, in one instance resulting in eight additional hours spent on debugging code.
Due to our proactive defense efforts, FlyingYeti operators adapted their tactics multiple times in their attempts to launch the campaign. The actor originally intended to have the Cloudflare Worker fetch the malicious RAR file from GitHub. After Cloudforce One interdiction of the Worker, the actor attempted to create additional Workers via a new account. In response, we disabled all Workers, leading the actor to load the RAR file directly from GitHub. Cloudforce One notified GitHub, resulting in the takedown of the RAR file, the GitHub project, and suspension of the account used to host the RAR file. In return, FlyingYeti began testing the option to host the RAR file on the file sharing sites pixeldrain and Filemail, where we observed the actor alternating the link on the Komunalka phishing site between the following:
We notified GitHub of the actor’s evolving tactics, and in response GitHub removed the Komunalka phishing site. After analyzing the files hosted on pixeldrain and Filemail, we determined the actor uploaded dummy payloads, likely to monitor access to their phishing infrastructure (FileMail logs IP addresses, and both file hosting sites provide view and download counts). At the time of publication, we did not observe FlyingYeti upload the malicious RAR file to either file hosting site, nor did we identify the use of alternative phishing or malware delivery methods.
A timeline of FlyingYeti’s activity and our corresponding mitigations can be found below.
Event timeline
Date
Event Description
2024-04-18 12:18
Threat Actor (TA) creates a Worker to handle requests from a phishing site
2024-04-18 14:16
TA creates phishing site komunalka[.]github[.]io on GitHub
2024-04-25 12:25
TA creates a GitHub repo to host a RAR file
2024-04-26 07:46
TA updates the first Worker to handle requests from users visiting komunalka[.]github[.]io
2024-04-26 08:24
TA uploads a benign test RAR to the GitHub repo
2024-04-26 13:38
Cloudforce One identifies a Worker receiving requests from users visiting komunalka[.]github[.]io, observes its use as a phishing page
2024-04-26 13:46
Cloudforce One identifies that the Worker fetches a RAR file from GitHub (the malicious RAR payload is not yet hosted on the site)
2024-04-26 19:22
Cloudforce One creates a detection to identify the Worker that fetches the RAR
2024-04-26 21:13
Cloudforce One deploys real-time monitoring of the RAR file on GitHub
2024-05-02 06:35
TA deploys a weaponized RAR (CVE-2023-38831) to GitHub with their COOKBOX malware packaged in the archive
2024-05-06 10:03
TA attempts to update the Worker with link to weaponized RAR, the Worker is immediately blocked
2024-05-06 10:38
TA creates a new Worker, the Worker is immediately blocked
2024-05-06 11:04
TA creates a new account (#2) on Cloudflare
2024-05-06 11:06
TA creates a new Worker on account #2 (blocked)
2024-05-06 11:50
TA creates a new Worker on account #2 (blocked)
2024-05-06 12:22
TA creates a new modified Worker on account #2
2024-05-06 16:05
Cloudforce One disables the running Worker on account #2
2024-05-07 22:16
TA notices the Worker is blocked, ceases all operations
2024-05-07 22:18
TA deletes original Worker first created to fetch the RAR file from the GitHub phishing page
2024-05-09 19:28
Cloudforce One adds phishing page komunalka[.]github[.]io to real-time monitoring
2024-05-13 07:36
TA updates the github.io phishing site to point directly to the GitHub RAR link
2024-05-13 17:47
Cloudforce One adds COOKBOX C2 postdock[.]serveftp[.]com to real-time monitoring for DNS resolution
2024-05-14 00:04
Cloudforce One notifies GitHub to take down the RAR file
2024-05-15 09:00
GitHub user, project, and link for RAR are no longer accessible
2024-05-21 08:23
TA updates Komunalka phishing site on github.io to link to pixeldrain URL for dummy payload (pixeldrain only tracks view and download counts)
2024-05-21 08:25
TA updates Komunalka phishing site to link to FileMail URL for dummy payload (FileMail tracks not only view and download counts, but also IP addresses)
2024-05-21 12:21
Cloudforce One downloads PixelDrain document to evaluate payload
2024-05-21 12:47
Cloudforce One downloads FileMail document to evaluate payload
2024-05-29 23:59
GitHub takes down Komunalka phishing site
2024-05-30 13:00
Cloudforce One publishes the results of this investigation
Coordinating our FlyingYeti response
Cloudforce One leveraged industry relationships to provide advanced warning and to mitigate the actor’s activity. To further protect the intended targets from this phishing threat, Cloudforce One notified and collaborated closely with GitHub’s Threat Intelligence and Trust and Safety Teams. We also notified CERT-UA and Cloudflare industry partners such as CrowdStrike, Mandiant/Google Threat Intelligence, and Microsoft Threat Intelligence.
Hunting FlyingYeti operations
There are several ways to hunt FlyingYeti in your environment. These include using PowerShell to hunt for WinRAR files, deploying Microsoft Sentinel analytics rules, and running Splunk scripts as detailed below. Note that these detections may identify activity related to this threat, but may also trigger unrelated threat activity.
PowerShell hunting
Consider running a PowerShell script such as this one in your environment to identify exploitation of CVE-2023-38831. This script will interrogate WinRAR files for evidence of the exploit.
CVE-2023-38831
Description:winrar exploit detection
open suspios (.tar / .zip / .rar) and run this script to check it

function winrar-exploit-detect(){
$targetExtensions = @(".cmd" , ".ps1" , ".bat")
$tempDir = [System.Environment]::GetEnvironmentVariable("TEMP")
$dirsToCheck = Get-ChildItem -Path $tempDir -Directory -Filter "Rar*"
foreach ($dir in $dirsToCheck) {
    $files = Get-ChildItem -Path $dir.FullName -File
    foreach ($file in $files) {
        $fileName = $file.Name
        $fileExtension = [System.IO.Path]::GetExtension($fileName)
        if ($targetExtensions -contains $fileExtension) {
            $fileWithoutExtension = [System.IO.Path]::GetFileNameWithoutExtension($fileName); $filename.TrimEnd() -replace '\.$'
            $cmdFileName = "$fileWithoutExtension"
            $secondFile = Join-Path -Path $dir.FullName -ChildPath $cmdFileName

            if (Test-Path $secondFile -PathType Leaf) {
                Write-Host "[!] Suspicious pair detected "
                Write-Host "[*]  Original File:$($secondFile)" -ForegroundColor Green
                Write-Host "[*] Suspicious File:$($file.FullName)" -ForegroundColor Red

                # Read and display the content of the command file
                $cmdFileContent = Get-Content -Path $($file.FullName)
                Write-Host "[+] Command File Content:$cmdFileContent"
            }
        }
    }
}
}
winrar-exploit-detect
Microsoft Sentinel
In Microsoft Sentinel, consider deploying the rule provided below, which identifies WinRAR execution via cmd.exe. Results generated by this rule may be indicative of attack activity on the endpoint and should be analyzed.
DeviceProcessEvents
| where InitiatingProcessParentFileName has @"winrar.exe"
| where InitiatingProcessFileName has @"cmd.exe"
| project Timestamp, DeviceName, FileName, FolderPath, ProcessCommandLine, AccountName
| sort by Timestamp desc
Splunk
Consider using this script in your Splunk environment to look for WinRAR CVE-2023-38831 execution on your Microsoft endpoints. Results generated by this script may be indicative of attack activity on the endpoint and should be analyzed.
| tstats `security_content_summariesonly` count min(_time) as firstTime max(_time) as lastTime from datamodel=Endpoint.Processes where Processes.parent_process_name=winrar.exe `windows_shells` OR Processes.process_name IN ("certutil.exe","mshta.exe","bitsadmin.exe") by Processes.dest Processes.user Processes.parent_process_name Processes.parent_process Processes.process_name Processes.process Processes.process_id Processes.parent_process_id
| `drop_dm_object_name(Processes)`
| `security_content_ctime(firstTime)`
| `security_content_ctime(lastTime)`
| `winrar_spawning_shell_application_filter`
Cloudflare product detections
Cloudflare Email Security
Cloudflare Email Security (CES) customers can identify FlyingYeti threat activity with the following detections.
CVE-2023-38831
FLYINGYETI.COOKBOX
FLYINGYETI.COOKBOX.Launcher
FLYINGYETI.Rar
Recommendations
Cloudflare recommends taking the following steps to mitigate this type of activity:
Implement Zero Trust architecture foundations:
Deploy Cloud Email Security to ensure that email services are protected against phishing, BEC and other threats
Leverage browser isolation to separate messaging applications like LinkedIn, email, and Signal from your main network
Scan, monitor and/or enforce controls on specific or sensitive data moving through your network environment with data loss prevention policies
Ensure your systems have the latest WinRAR and Microsoft security updates installed
Consider preventing WinRAR files from entering your environment, both at your Cloud Email Security solution and your Internet Traffic Gateway
Run an Endpoint Detection and Response (EDR) tool such as CrowdStrike or Microsoft Defender for Endpoint to get visibility into binary execution on hosts
Search your environment for the FlyingYeti indicators of compromise (IOCs) shown below to identify potential actor activity within your network.
If you’re looking to uncover additional Threat Intelligence insights for your organization or need bespoke Threat Intelligence information for an incident, consider engaging with Cloudforce One by contacting your Customer Success manager or filling out this form.
In April 2020, we blogged about how to get COBOL running on Cloudflare Workers by compiling to WebAssembly. The ecosystem around WebAssembly has grown significantly since then, and it has become a solid foundation for all types of projects, be they client-side or server-side.
As WebAssembly support has grown, more and more languages are able to compile to WebAssembly for execution on servers and in browsers. As Cloudflare Workers uses the V8 engine and supports WebAssembly natively, we’re able to support languages that compile to WebAssembly on the platform.
Recently, work on LLVM has enabled Fortran to compile to WebAssembly. So, today, we’re writing about running Fortran code on Cloudflare Workers.
Before we dive into how to do this, here’s a little demonstration of number recognition in Fortran. Draw a number from 0 to 9 and Fortran code running somewhere on Cloudflare’s network will predict the number you drew.
This is taken from the wonderful Fortran on WebAssembly post but instead of running client-side, the Fortran code is running on Cloudflare Workers. Read on to find out how you can use Fortran on Cloudflare Workers and how that demonstration works.
Wait, Fortran? No one uses that!
Not so fast! Or rather, actually pretty darn fast if you’re doing a lot of numerical programming or have scientific data to work with. Fortran (originally FORmula TRANslator) is very well suited for scientific workloads because of its native functionality for things like arithmetic and handling large arrays and matrices.
If you look at the ranking of the fastest supercomputers in the world you’ll discover that the measurement of “fast” is based on these supercomputers running a piece of software called LINPACK that was originally written in Fortran. LINPACK is designed to help with problems solvable using linear algebra.
The LINPACK benchmarks use LINPACK to solve an n x n system of linear equations using matrix operations and, in doing so, determine how fast supercomputers are. The code is available in Fortran, C and Java.
A related Fortran package, BLAS, also does linear algebra and forms the basis of the number identifying code above. But other Fortran packages are still relevant. Back in 2017, NASA ran a competition to make FUN3D (used to perform calculations of airflow over simulated aircraft). FUN3D is written in Fortran.
So, although Fortran (or at the time FORTRAN) first came to life in 1957, it’s alive and well and being used widely for scientific applications (there’s even Fortran for CUDA). One particular application left Earth 20 years after Fortran was born: Voyager. The Voyager probes use a combination of assembly language and Fortran to keep chugging along.
But back in our solar system, and back on Region: Earth, you can now use Fortran on Cloudflare Workers. Here’s how.
How to get your Fortran code running on Cloudflare Workers
To make it easy to run your Fortran code on Cloudflare Workers, we created a tool called Fortiche (translates to smart in French). It uses Flang and Emscripten under the hood.
Flang is a frontend in LLVM and, if you read the Fortran on WebAssembly blog post, we currently have to patch LLVM to work around a few issues.
Emscripten is used to compile LLVM output and produce code that is compatible with Cloudflare Workers.
This is all packaged in the Fortiche Docker image. Let’s see a simple example.
add.f90:
SUBROUTINE add(a, b, res)
    INTEGER, INTENT(IN) :: a, b
    INTEGER, INTENT(OUT) :: res

    res = a + b
END
Here we defined a subroutine called add that takes a and b, sums them together and places the result in res.
docker run -v $PWD:/input -v $PWD/output:/output xtuc/fortiche --export-func=add add.f90
Passing --export-func=add to Fortiche makes the Fortran add subroutine available to JavaScript.
The output folder contains the compiled WebAssembly module and JavaScript from Emscripten, and a JavaScript endpoint generated by Fortiche:
$ ls -lh ./output
total 84K
-rw-r--r-- 1 root root 392 avril 22 12:00 index.mjs
-rw-r--r-- 1 root root 27K avril 22 12:00 out.mjs
-rwxr-xr-x 1 root root 49K avril 22 12:00 out.wasm
And finally the Cloudflare Worker:
// Import what Fortiche generated
import {load} from "../output/index.mjs"

export default {
    async fetch(request: Request): Promise<Response> {
        // Load the Fortran program
        const program = await load();

        // Allocate space in memory for the arguments and result
        const aPtr = program.malloc(4);
        const bPtr = program.malloc(4);
        const outPtr = program.malloc(4);

        // Set argument values
        program.HEAP32[aPtr / 4] = 123;
        program.HEAP32[bPtr / 4] = 321;

        // Run the Fortran add subroutine
        program.add(aPtr, bPtr, outPtr);

        // Read the result
        const res = program.HEAP32[outPtr / 4];

        // Free everything
        program.free(aPtr);
        program.free(bPtr);
        program.free(outPtr);

        return Response.json({ res });
    },
};
Interestingly, the values we pass to Fortran are all pointers, therefore we have to allocate space for each argument and result (the Fortran integer type is four bytes wide), and pass the pointers to the `add` subroutine.
Workers AI’s initial launch in beta included support for Llama 2, as it was one of the most requested open source models from the developer community. Since that initial launch, we’ve seen developers build all kinds of innovative applications including knowledge sharing chatbots, creative content generation, and automation for various workflows.
At Cloudflare, we know developers want simplicity and flexibility, with the ability to build with multiple AI models while optimizing for accuracy, performance, and cost, among other factors. Our goal is to make it as easy as possible for developers to use their models of choice without having to worry about the complexities of hosting or deploying models.
As soon as we learned about the development of Llama 3 from our partners at Meta, we knew developers would want to start building with it as quickly as possible. Workers AI’s serverless inference platform makes it extremely easy and cost effective to start using the latest large language models (LLMs). Meta’s commitment to developing and growing an open AI-ecosystem makes it possible for customers of all sizes to use AI at scale in production. All it takes is a few lines of code to run inference to Llama 3:
export interface Env {
  // If you set another name in wrangler.toml as the value for 'binding',
  // replace "AI" with the variable name you defined.
  AI: any;
}

export default {
  async fetch(request: Request, env: Env) {
    const response = await env.AI.run('@cf/meta/llama-3-8b-instruct', {
        messages: [
{role: "user", content: "What is the origin of the phrase Hello, World?"}
	 ]
      }
    );

    return new Response(JSON.stringify(response));
  },
};
Built with Meta Llama 3
Llama 3 offers leading performance on a wide range of industry benchmarks. You can learn more about the architecture and improvements on Meta’s blog post. Cloudflare Workers AI supports Llama 3 8B, including the instruction fine-tuned model.
Meta’s testing shows that Llama 3 is the most advanced open LLM today on evaluation benchmarks such as MMLU, GPQA, HumanEval, GSM-8K, and MATH. Llama 3 was trained on an increased number of training tokens (15T), allowing the model to have a better grasp on language intricacies. Larger context windows doubles the capacity of Llama 2, and allows the model to better understand lengthy passages with rich contextual data. Although the model supports a context window of 8k, we currently only support 2.8k but are looking to support 8k context windows through quantized models soon. As well, the new model introduces an efficient new tiktoken-based tokenizer with a vocabulary of 128k tokens, encoding more characters per token, and achieving better performance on English and multilingual benchmarks. This means that there are 4 times as many parameters in the embedding and output layers, making the model larger than the previous Llama 2 generation of models.
Under the hood, Llama 3 uses grouped-query attention (GQA), which improves inference efficiency for longer sequences and also renders their 8B model architecturally equivalent to Mistral-7B. For tokenization, it uses byte-level byte-pair encoding (BPE), similar to OpenAI’s GPT tokenizers. This allows tokens to represent any arbitrary byte sequence — even those without a valid utf-8 encoding. This makes the end-to-end model much more flexible in its representation of language, and leads to improved performance.
Along with the base Llama 3 models, Meta has released a suite of offerings with tools such as Llama Guard 2, Code Shield, and CyberSec Eval 2, which we are hoping to release on our Workers AI platform shortly.
Developer Week 2024 has officially come to a close. Each day last week, we shipped new products and functionality geared towards giving developers the components they need to build full-stack applications on Cloudflare.
Even though Developer Week is now over, we are continuing to innovate with the over two million developers who build on our platform. Building a platform is only as exciting as seeing what developers build on it. Before we dive into a recap of the announcements, to send off the week, we wanted to share how a couple of companies are using Cloudflare to power their applications:
We have been using Workers for image delivery using R2 and have been able to maintain stable operations for a year after implementation. The speed of deployment and the flexibility of detailed configurations have greatly reduced the time and effort required for traditional server management. In particular, we have seen a noticeable cost savings and are deeply appreciative of the support we have received from Cloudflare Workers. – FAN Communications
Milkshake helps creators, influencers, and business owners create engaging web pages directly from their phone, to simply and creatively promote their projects and passions. Cloudflare has helped us migrate data quickly and affordably with R2. We use Workers as a routing layer between our users’ websites and their images and assets, and to build a personalized analytics offering affordably. Cloudflare’s innovations have consistently allowed us to run infrastructure at a fraction of the cost of other developer platforms and we have been eagerly awaiting updates to D1 and Queues to sustainably scale Milkshake as the product continues to grow. – Milkshake
In case you missed anything, here’s a quick recap of the announcements and in-depth technical explorations that went out last week:
A core part of any full-stack application is storing and persisting data! We kicked off the week with announcements that help developers build stateful applications on top of Cloudflare, including making D1, Cloudflare’s SQL database and Hyperdrive, our database accelerating service, generally available.
D1, Cloudflare’s SQL database, is now generally available. With new support for 10GB databases, data export, and enhanced query debugging, we empower developers to build production-ready applications with D1 to meet all their relational SQL needs. To support Workers in global applications, we’re sharing a sneak peek of our design and API for D1 global read replication to demonstrate how developers scale their workloads with D1.
Bindings don’t just reduce boilerplate. They are a core design feature of the Workers platform which simultaneously improve developer experience and application security in several ways. Usually these two goals are in opposition to each other, but bindings elegantly solve for both at the same time.
We made a series of AI-related announcements, including Workers AI, Cloudflare’s inference platform becoming GA, support for fine-tuned models with LoRAs, one-click deploys from HuggingFace, Python support for Cloudflare Workers, and more.
Workers AI now supports fine-tuned models using LoRAs. But what is a LoRA and how does it work? In this post, we dive into fine-tuning, LoRAs and even some math to share the details of how it all works under the hood.
We introduced Python support for Cloudflare Workers, now in open beta. We’ve revamped our systems to support Python, from the Workers runtime itself to the way Workers are deployed to Cloudflare’s network. Learn about a Python Worker’s lifecycle, Pyodide, dynamic linking, and memory snapshots in this post.
We announced three new features for Cloudflare R2: event notifications, support for migrations from Google Cloud Storage, and an infrequent access storage tier.
We’re making it easier to build scalable, reliable, data-driven applications on top of our global network, and so we announced a new Event Notifications framework; our take on durable execution, Workflows; and an upcoming streaming ingestion service, Pipelines.
Together, Cloudflare and Prisma make it easier than ever to deploy globally available apps with a focus on developer experience. To further that goal, Prisma ORM now natively supports Cloudflare Workers and D1 in Preview. With version 5.12.0 of Prisma ORM you can now interact with your data stored in D1 from your Cloudflare Workers with the convenience of the Prisma Client API. Learn more and try it out now.
Picsart, one of the world’s largest digital creation platforms, encountered performance challenges in catering to its global audience. Adopting Cloudflare’s global-by-default Developer Platform emerged as the optimal solution, empowering Picsart to enhance performance and scalability substantially.
We launched four improvements to Pages that bring functionality previously restricted to Workers, with the goal of unifying the development experience between the two. Support for monorepos, wrangler.toml, new additions to Next.js support and database integrations!
Production readiness isn’t just about scale and reliability of the services you build with. We announced five updates that put more power in your hands – Gradual Deployments, Source mapped stack traces in Tail Workers, a new Rate Limiting API, brand-new API SDKs, and updates to Durable Objects – each built with mission-critical production services in mind.
With Cloudflare Calls in open beta, you can build real-time, serverless video and audio applications. Cloudflare Stream lets your viewers instantly clip from ongoing streams. Finally, Cloudflare Images now supports automatic face cropping and has an upload widget that lets you easily integrate into your application.
Cloudflare Calls is a serverless SFU and TURN service running at Cloudflare’s edge. It’s now in open beta and costs $0.05/ real-time GB. It’s 100% anycast WebRTC.
We announced that PartyKit, a trailblazer in enabling developers to craft ambitious real-time, collaborative, multiplayer applications, is now a part of Cloudflare. This acquisition marks a significant milestone in our journey to redefine the boundaries of serverless computing, making it more dynamic, interactive, and, importantly, stateful.
Full-stack web development with Cloudflare is now faster and easier! You can now use your framework’s development server while accessing D1 databases, R2 object stores, AI models, and more. Iterate locally in milliseconds to build sophisticated web apps that run on Cloudflare. Let’s dev together!
Cloudflare Workers now features a built-in RPC (Remote Procedure Call) system for use in Worker-to-Worker and Worker-to-Durable Object communication, with absolutely minimal boilerplate. We’ve designed an RPC system so expressive that calling a remote service can feel like using a library.
We closed out Developer Week by sharing updates on our Workers Launchpad program, our latest Developer Challenge, and the work we’re doing to ensure our community spaces – like our Discord and Community forums – are safe and inclusive for all developers.
Continue the conversation
Thank you for being a part of Developer Week! Want to continue the conversation and share what you’re building? Join us on Discord. To get started building on Workers, check out our developer documentation.
The cloud is changing. Just a few years ago, serverless functions were revolutionary. Today, entire applications are built on serverless architectures, from compute to databases, storage, queues, etc. — with Cloudflare leading the way in making it easier than ever for developers to build, without having to think about their architecture. And while the adoption of serverless has made it simple for developers to run fast, it has also made one of the most difficult problems in software even harder: how the heck do you unravel the behavior of distributed systems?
When I started Baselime 2 years ago, our goal was simple: enable every developer to build, ship, and learn from their serverless applications such that they can resolve issues before they become problems.
Since then, we built an observability platform that enables developers to understand the behaviour of their cloud applications. It’s designed for high cardinality and dimensionality data, from logs to distributed tracing with OpenTelemetry. With this data, we automatically surface insights from your applications, and enable you to quickly detect, troubleshoot, and resolve issues in production.
In parallel, Cloudflare has been busy the past few years building the next frontier of cloud computing: the connectivity cloud. The team is building primitives that enable developers to build applications with a completely new set of paradigms, from Workers to D1, R2, Queues, KV, Durable Objects, AI, and all the other services available on the Cloudflare Developers Platform.
This synergy makes Cloudflare the perfect home for Baselime. Our core mission has always been to simplify and innovate around observability for the future of the cloud, and Cloudflare’s ecosystem offers the ideal ground to further this cause. With Cloudflare, we’re positioned to deeply integrate into a platform that tens of thousands of developers trust and use daily, enabling them to quickly build, ship, and troubleshoot applications. We believe that every Worker, Queue, KV, Durable Object, AI call, etc. should have built-in observability by default.
That’s why we’re incredibly excited about the potential of what we can build together and the impact it will have on developers around the world.
To give you a preview into what’s ahead, I wanted to dive deeper into the 3 core concepts we followed while building Baselime.
High Cardinality and Dimensionality
Cardinality and dimensionality are best described using examples. Imagine you’re playing a board game with a deck of cards. High cardinality is like playing a game where every card is a unique character, making it hard to remember or match them. And high dimensionality is like each card has tons of details like strength, speed, magic, aura, etc., making the game’s strategy complex because there’s so much to consider.
This also applies to the data your application emits. For example, when you log an HTTP request that makes database calls.
High cardinality means that your logs can have a unique userId or requestId (which can take millions of distinct values). Those are high cardinality fields.
High dimensionality means that your logs can have thousands of possible fields. You can record each HTTP header of your request and the details of each database call. Any log can be a key-value object with thousands of individual keys.
The ability to query on high cardinality and dimensionality fields is key to modern observability. You can surface all errors or requests for a specific user, compute the duration of each of those requests, and group by location. You can answer all of those questions with a single tool.
OpenTelemetry
OpenTelemetry provides a common set of tools, APIs, SDKs, and standards for instrumenting applications. It is a game-changer for debugging and understanding cloud applications. You get to see the big picture: how fast your HTTP APIs are, which routes are experiencing the most errors, or which database queries are slowest. You can also get into the details by following the path of a single request or user across your entire application.
Baselime is OpenTelemetry native, and it is built from the ground up to leverage OpenTelemetry data. To support this, we built a set of OpenTelemetry SDKs compatible with several serverless runtimes.
Cloudflare is building the cloud of tomorrow and has developed workerd, a modern JavaScript runtime for Workers. With Cloudflare, we are considering embedding OpenTelemetry directly in the Workers’ runtime. That’s one more reason we’re excited to grow further at Cloudflare, enabling more developers to understand their applications, even in the most unconventional scenarios.
Developer Experience
Observability without action is just storage. I have seen too many developers pay for tools to store logs and metrics they never use, and the key reason is how opaque these tools are.
The crux of the issue in modern observability isn’t the technology itself, but rather the developer experience. Many tools are complex, with a significant learning curve. This friction reduces the speed at which developers can identify and resolve issues, ultimately affecting the reliability of their applications. Improving developer experience is key to unlocking the full potential of observability.
We built Baselime to be an exploratory solution that surfaces insights to you rather than requiring you to dig for them. For example, we notify you in real time when errors are discovered in your application, based on your logs and traces. You can quickly search through all of your data with full-text search, or using our powerful query engine, which makes it easy to correlate logs and traces for increased visibility, or ask our AI debugging assistant for insights on the issue you’re investigating.
It is always possible to go from one insight to another, asking questions about the state of your app iteratively until you get to the root cause of the issue you are troubleshooting.
Cloudflare has always prioritised the developer experience of its developer platform, especially with Wrangler, and we are convinced it’s the right place to solve the developer experience problem of observability.
What’s next?
Over the next few months, we’ll work to bring the core of Baselime into the Cloudflare ecosystem, starting with OpenTelemetry, real-time error tracking, and all the developer experience capabilities that make a great observability solution. We will keep building and improving observability for applications deployed outside Cloudflare because we understand that observability should work across providers.
But we don’t want to stop there. We want to push the boundaries of what modern observability looks like. For instance, directly connecting to your codebase and correlating insights from your logs and traces to functions and classes in your codebase. We also want to enable more AI capabilities beyond our debugging assistant. We want to deeply integrate with your repositories such that you can go from an error in your logs and traces to a Pull Request in your codebase within minutes.
We also want to enable everyone building on top of Large Language Models to do all your LLM observability directly within Cloudflare, such that you can optimise your prompts, improve latencies and reduce error rates directly within your cloud provider. These are just a handful of capabilities we can now build with the support of the Cloudflare platform.
Thanks
We are incredibly thankful to our community for its continued support, from day 0 to today. With your continuous feedback, you’ve helped us build something we’re incredibly proud of.
To all the developers currently using Baselime, you’ll be able to keep using the product and will receive ongoing support. Also, we are now making all the paid Baselime features completely free.
Baselime products remain available to sign up for while we work on integrating with the Cloudflare platform. We anticipate sunsetting the Baselime products towards the end of 2024 when you will be able to observe all of your applications within the Cloudflare dashboard. If you’re interested in staying up-to-date on our work with Cloudflare, we will release a signup link in the coming weeks!
We are looking forward to continuing to innovate with you.
We’re thrilled to announce that PartyKit, an open source platform for deploying real-time, collaborative, multiplayer applications, is now a part of Cloudflare. This acquisition marks a significant milestone in our journey to redefine the boundaries of serverless computing, making it more dynamic, interactive, and, importantly, stateful.
Defining the future of serverless compute around state
Building real-time applications on the web have always been difficult. Not only is it a distributed systems problem, but you need to provision and manage infrastructure, databases, and other services to maintain state across multiple clients. This complexity has traditionally been a barrier to entry for many developers, especially those who are just starting out.
We announced Durable Objects in 2020 as a way of building synchronized real time experiences for the web. Unlike regular serverless functions that are ephemeral and stateless, Durable Objects are stateful, allowing developers to build applications that maintain state across requests. They also act as an ideal synchronization point for building real-time applications that need to maintain state across multiple clients. Combined with WebSockets, Durable Objects can be used to build a wide range of applications, from multiplayer games to collaborative drawing tools.
In 2022, PartyKit began as a project to further explore the capabilities of Durable Objects and make them more accessible to developers by exposing them through familiar components. In seconds, you could create a project that configured behavior for these objects, and deploy it to Cloudflare. By integrating with popular libraries such as Yjs (the gold standard in collaborative editing) and React, PartyKit made it possible for developers to build a wide range of use cases, from multiplayer games to collaborative drawing tools, into their applications.
Building experiences with real-time components was previously only accessible to multi-billion dollar companies, but new computing primitives like Durable Objects on the edge make this accessible to regular developers and teams. With PartyKit now under our roof, we’re doubling down on our commitment to this future — a future where serverless is stateful.
We’re excited to give you a preview into our shared vision for applications, and the use cases we’re excited to simplify together.
Making state for serverless easy
Unlike conventional approaches that rely on external databases to maintain state, thereby complicating scalability and increasing costs, PartyKit leverages Cloudflare’s Durable Objects to offer a seamless model where stateful serverless functions can operate as if they were running on a single machine, maintaining state across requests. This innovation not only simplifies development but also opens up a broader range of use cases, including real-time computing, collaborative editing, and multiplayer gaming, by allowing thousands of these “machines” to be spun up globally, each maintaining its own state. PartyKit aims to be a complement to traditional serverless computing, providing a more intuitive and efficient method for developing applications that require stateful behavior, thereby marking the “next evolution” of serverless computing.
Simplifying WebSockets for Real-Time Interaction
WebSockets have revolutionized how we think about bidirectional communication on the web. Yet, the challenge has always been about scaling these interactions to millions without a hitch. Cloudflare Workers step in as the hero, providing a serverless framework that makes real-time applications like chat services, multiplayer games, and collaborative tools not just possible but scalable and efficient.
Powering Games and Multiplayer Applications Without Limits
Imagine building multiplayer platforms where the game never lags, the collaboration is seamless, and video conferences are crystal clear. Cloudflare’s Durable Objects morph the stateless serverless landscape into a realm where persistent connections thrive. PartyKit’s integration into this ecosystem means developers now have a powerhouse toolkit to bring ambitious multiplayer visions to life, without the traditional overheads.
This is especially critical in gaming — there are few areas where low-latency and real-time interaction matter more. Every millisecond, every lag, every delay defines the entire experience. With PartyKit’s capabilities integrated into Cloudflare, developers will be able to leverage our combined technologies to create gaming experiences that are not just about playing but living the game, thanks to scalable, immersive, and interactive platforms.
The toolkit for building Local-First applications
The Internet is great, and increasingly always available, but there are still a few situations where we are forced to disconnect — whether on a plane, a train, or a beach.
The premise of local-first applications is that work doesn’t stop when the Internet does. Wherever you left off in your doc, you can keep working on it, assuming the state will be restored when you come back online. By storing data on the client and syncing when back online, these applications offer resilience and responsiveness that’s unmatched. Cloudflare’s vision, enhanced by PartyKit’s technology, aims to make local-first not just an option but the standard for application development.
What’s next for PartyKit users?
Users can expect their existing projects to continue working as expected. We will be adding more features to the platform, including the ability to create and use PartyKit projects inside existing Workers and Pages projects. There will be no extra charges to use PartyKit for commercial purposes, other than the standard usage charges for Cloudflare Workers and other services. Further, we’re going to expand the roadmap to begin working on integrations with popular frameworks and libraries, such as React, Vue, and Angular. We’re deeply committed to executing on the PartyKit vision and roadmap, and we’re excited to see what you build with it.
The Beginning of a New Chapter
The acquisition of PartyKit by Cloudflare isn’t just a milestone for our two teams; it’s a leap forward for developers everywhere. Together, we’re not just building tools; we’re crafting the foundation for the next generation of Internet applications. The future of serverless is stateful, and with PartyKit’s expertise now part of our arsenal, we’re more ready than ever to make that future a reality.
Welcome to the Cloudflare team, PartyKit. Look forward to building something remarkable together.
Cloudflare Workers now features a built-in RPC (Remote Procedure Call) system enabling seamless Worker-to-Worker and Worker-to-Durable Object communication, with almost no boilerplate. You just define a class:
export class MyService extends WorkerEntrypoint {
  sum(a, b) {
    return a + b;
  }
}
And then you call it:
let three = await env.MY_SERVICE.sum(1, 2);
No schemas. No routers. Just define methods of a class. Then call them. That’s it.
But that’s not it
This isn’t just any old RPC. We’ve designed an RPC system so expressive that calling a remote service can feel like using a library – without any need to actually import a library! This is important not just for ease of use, but also security: fewer dependencies means fewer critical security updates and less exposure to supply-chain attacks.
To this end, here are some of the features of Workers RPC:
For starters, you can pass Structured Clonable types as the params or return value of an RPC. (That means that, unlike JSON, Dates just work, and you can even have cycles.)
You can additionally pass functions in the params or return value of other functions. When the other side calls the function you passed to it, they make a new RPC back to you.
Similarly, you can pass objects with methods. Method calls become further RPCs.
RPC to another Worker (over a Service Binding) usually does not even cross a network. In fact, the other Worker usually runs in the very same thread as the caller, reducing latency to zero. Performance-wise, it’s almost as fast as an actual function call.
When RPC does cross a network (e.g. to a Durable Object), you can invoke a method and then speculatively invoke further methods on the result in a single network round trip.
You can send a byte stream over RPC, and the system will automatically stream the bytes with proper flow control.
All of this is secure, based on the object-capability model.
Workers RPC is a JavaScript-native RPC system. Under the hood, it is built on Cap’n Proto. However, unlike Cap’n Proto, Workers RPC does not require you to write a schema. (Of course, you can use TypeScript if you like, and we provide tools to help with this.)
In general, Workers RPC is designed to “just work” using idiomatic JavaScript code, so you shouldn’t have to spend too much time looking at docs. We’ll give you an overview in this blog post. But if you want to understand the full feature set, check out the documentation.
Why RPC? (And what is RPC anyway?)
Remote Procedure Calls (RPC) are a way of expressing communications between two programs over a network. Without RPC, you might communicate using a protocol like HTTP. With HTTP, though, you must format and parse your communications as an HTTP request and response, perhaps designed in REST style. RPC systems try to make communications look like a regular function call instead, as if you were calling a library rather than a remote service. The RPC system provides a “stub” object on the client side which stands in for the real server-side object. When a method is called on the stub, the RPC system figures out how to serialize and transmit the parameters to the server, invoke the method on the server, and then transmit the return value back.
The merits of RPC have been subject to a great deal of debate. RPC is often accused of committing many of the fallacies of distributed computing.
But this reputation is outdated. When RPC was first invented some 40 years ago, async programming barely existed. We did not have Promises, much less async and await. Early RPC was synchronous: calls would block the calling thread waiting for a reply. At best, latency made the program slow. At worst, network failures would hang or crash the program. No wonder it was deemed “broken”.
Things are different today. We have Promise and async and await, and we can throw exceptions on network failures. We even understand how RPCs can be pipelined so that a chain of calls takes only one network round trip. Many large distributed systems you likely use every day are built on RPC. It works.
The fact is, RPC fits the programming model we’re used to. Every programmer is trained to think in terms of APIs composed of function calls, not in terms of byte stream protocols nor even REST. Using RPC frees you from the need to constantly translate between mental models, allowing you to move faster.
Example: Authentication Service
Here’s a common scenario: You have one Worker that implements an application, and another Worker that is responsible for authenticating user credentials. The app Worker needs to call the auth Worker on each request to check the user’s cookie.
This example uses a Service Binding, which is a way of configuring one Worker with a private channel to talk to another, without going through a public URL. Here, we have an application Worker that has been configured with a service binding to the Auth worker.
Before RPC, all communications between Workers needed to use HTTP. So, you might write code like this:
// OLD STYLE: HTTP-based service bindings.
export default {
  async fetch(req, env, ctx) {
    // Call the auth service to authenticate the user's cookie.
    // We send it an HTTP request using a service binding.

    // Construct a JSON request to the auth service.
    let authRequest = {
      cookie: req.headers.get("Cookie")
    };

    // Send it to env.AUTH_SERVICE, which is our service binding
    // to the auth worker.
    let resp = await env.AUTH_SERVICE.fetch(
        "https://auth/check-cookie", {
      method: "POST",
      headers: {
        "Content-Type": "application/json; charset=utf-8",
      },
      body: JSON.stringify(authRequest)
    });

    if (!resp.ok) {
      return new Response("Internal Server Error", {status: 500});
    }

    // Parse the JSON result.
    let authResult = await resp.json();

    // Use the result.
    if (!authResult.authorized) {
      return new Response("Not authorized", {status: 403});
    }
    let username = authResult.username;

    return new Response(`Hello, ${username}!`);
  }
}
Meanwhile, your auth server might look like:
// OLD STYLE: HTTP-based auth server.
export default {
  async fetch(req, env, ctx) {
    // Parse URL to decide what endpoint is being called.
    let url = new URL(req.url);
    if (url.pathname == "/check-cookie") {
      // Parse the request.
      let authRequest = await req.json();

      // Look up cookie in Workers KV.
      let cookieInfo = await env.COOKIE_MAP.get(
          hash(authRequest.cookie), "json");

      // Construct the response.
      let result;
      if (cookieInfo) {
        result = {
          authorized: true,
          username: cookieInfo.username
        };
      } else {
        result = { authorized: false };
      }

      return Response.json(result);
    } else {
      return new Response("Not found", {status: 404});
    }
  }
}
This code has a lot of boilerplate involved in setting up an HTTP request to the auth service. With RPC, we can instead express this as a function call:
// NEW STYLE: RPC-based service bindings
export default {
  async fetch(req, env, ctx) {
    // Call the auth service to authenticate the user's cookie.
    // We invoke it using a service binding.
    let authResult = await env.AUTH_SERVICE.checkCookie(
        req.headers.get("Cookie"));

    // Use the result.
    if (!authResult.authorized) {
      return new Response("Not authorized", {status: 403});
    }
    let username = authResult.username;

    return new Response(`Hello, ${username}!`);
  }
}
And the server side becomes:
// NEW STYLE: RPC-based auth server.
import { WorkerEntrypoint } from "cloudflare:workers";

export class AuthService extends WorkerEntrypoint {
  async checkCookie(cookie) {
    // Look up cookie in Workers KV.
    let cookieInfo = await this.env.COOKIE_MAP.get(
        hash(cookie), "json");

    // Return result.
    if (cookieInfo) {
      return {
        authorized: true,
        username: cookieInfo.username
      };
    } else {
      return { authorized: false };
    }
  }
}
This is a pretty nice simplification… but we can do much more!
Let’s get fancy! Or should I say… classy?
Let’s say we want our auth service to do a little more. Instead of just checking cookies, it provides a whole API around user accounts. In particular, it should let you:
Get or update the user’s profile info.
Send the user an email notification.
Append to the user’s activity log.
But, these operations should only be allowed after presenting the user’s credentials.
Here’s what the server might look like:
import { WorkerEntrypoint, RpcTarget } from "cloudflare:workers";

// `User` is an RPC interface to perform operations on a particular
// user. This class is NOT exported as an entrypoint; it must be
// received as the result of the checkCookie() RPC.
class User extends RpcTarget {
  constructor(uid, env) {
    super();

    // Note: Instance members like these are NOT exposed over RPC.
    // Only class (prototype) methods and properties are exposed.
    this.uid = uid;
    this.env = env;
  }

  // Get/set user profile, backed by Worker KV.
  async getProfile() {
    return await this.env.PROFILES.get(this.uid, "json");
  }
  async setProfile(profile) {
    await this.env.PROFILES.put(this.uid, JSON.stringify(profile));
  }

  // Send the user a notification email.
  async sendNotification(message) {
    let addr = await this.env.EMAILS.get(this.uid);
    await this.env.EMAIL_SERVICE.send(addr, message);
  }

  // Append to the user's activity log.
  async logActivity(description) {
    // (Please excuse this somewhat problematic implementation,
    // this is just a dumb example.)
    let timestamp = new Date().toISOString();
    await this.env.ACTIVITY.put(
        `${this.uid}/${timestamp}`, description);
  }
}

// Now we define the entrypoint service, which can be used to
// get User instances -- but only by presenting the cookie.
export class AuthService extends WorkerEntrypoint {
  async checkCookie(cookie) {
    // Look up cookie in Workers KV.
    let cookieInfo = await this.env.COOKIE_MAP.get(
        hash(cookie), "json");

    if (cookieInfo) {
      return {
        authorized: true,
        user: new User(cookieInfo.uid, this.env),
      };
    } else {
      return { authorized: false };
    }
  }
}
Now we can write a Worker that uses this API while displaying a web page:
export default {
  async fetch(req, env, ctx) {
    // `using` is a new JavaScript feature. Check out the
    // docs for more on this:
    // https://developers.cloudflare.com/workers/runtime-apis/rpc/lifecycle/
    using authResult = await env.AUTH_SERVICE.checkCookie(
        req.headers.get("Cookie"));
    if (!authResult.authorized) {
      return new Response("Not authorized", {status: 403});
    }

    let user = authResult.user;
    let profile = await user.getProfile();

    await user.logActivity("You visited the site!");
    await user.sendNotification(
        `Thanks for visiting, ${profile.name}!`);

    return new Response(`Hello, ${profile.name}!`);
  }
}
Finally, this worker needs to be configured with a service binding pointing at the AuthService class. Its wrangler.toml may look like:
name = "app-worker"
main = "./src/app.js"

# Declare a service binding to the auth service.
[[services]]
binding = "AUTH_SERVICE"    # name of the binding in `env`
service = "auth-service"    # name of the worker in the dashboard
entrypoint = "AuthService"  # name of the exported RPC class
Wait, how?
What exactly happened here? The Server created an instance of the class User and returned it to the client. It has methods that the client can then just call? Are we somehow transferring code over the wire?
No, absolutely not! All code runs strictly in the isolate where it was originally loaded. What actually happens is, when the return value is passed over RPC, all class instances are replaced with RPC stubs. The stub, when called, makes a new RPC back to the server, where it calls the method on the original User object that was created there:
But then you might ask: how does the RPC stub know what methods are available? Is a list of methods passed over the wire?
In fact, no. The RPC stub is a special object called a “Proxy“. It implements a “wildcard method”, that is, it appears to have an infinite number of methods of every possible name. When you try to call a method, the name you called is sent to the server. If the original object has no such method, an exception is thrown.
Did you spot the security?
In the above example, we see that RPC is easy to use. We made an object! We called it! It all just felt natural, like calling a local API! Hooray!
But there’s another extremely important property that the AuthService API has which you may have missed: As designed, you cannot perform any operation on a user without first checking the cookie. This is true despite the fact that the individual method calls do not require sending the cookie again, and the User object itself doesn’t store the cookie.
The trick is, the initial checkCookie() RPC is what returns a User object in the first place. The AuthService API does not provide any other way to obtain a User instance. The RPC client cannot create a User object out of thin air, and cannot call methods of an object without first explicitly receiving a reference to it.
This is called capability-based security: we say that the User reference received by the client is a “capability”, because receiving it grants the client the ability to perform operations on the user. The getProfile() method grants this capability only when the client has presented the correct cookie.
Capability-based security is often like this: security can be woven naturally into your APIs, rather than feel like an additional concern bolted on top.
More security: Named entrypoints
Another subtle but important detail to call out: in the above example, the auth service’s RPC API is exported as a named class:
export class AuthService extends WorkerEntrypoint {
And in our wrangler.toml for the calling worker, we had to specify an “entrypoint”, matching the class name:
entrypoint = "AuthService" # name of the exported RPC class
In the past, service bindings would bind to the “default” entrypoint, declared with export default {. But, the default entrypoint is also typically exposed to the Internet, e.g. automatically mapped to a hostname under workers.dev (unless you explicitly turn that off). It can be tricky to safely assume that requests arriving at this entrypoint are in any way trusted.
With named entrypoints, this all changes. A named entrypoint is only accessible to Workers which have explicitly declared a binding to it. By default, only Workers on your own account can declare such bindings. Moreover, the binding must be declared at deploy time; a Worker cannot create new service bindings at runtime.
Thus, you can trust that requests arriving at a named entrypoint can only have come from Workers on your account and for which you explicitly created a service binding. In the future, we plan to extend this pattern further with the ability to lock down entrypoints, audit which Workers have bindings to them, tell the callee information about who is calling at runtime, and so on. With these tools, there is no need to write code in your app itself to authenticate access to internal APIs; the system does it for you.
What about type safety?
Workers RPC works in an entirely dynamically-typed way, just as JavaScript itself does. But just as you can apply TypeScript on top of JavaScript in general, you can apply it to Workers RPC.
The @cloudflare/workers-types package defines the type Service<MyEntrypointType>, which describes the type of a service binding. MyEntrypointType is the type of your server-side interface. Service<MyEntrypointType> applies all the necessary transformations to turn this into a client-side type, such as converting all methods to async, replacing functions and RpcTargets with (properly-typed) stubs, and so on.
It is up to you to share the definition of MyEntrypointType between your server app and its clients. You might do this by defining the interface in a separate shared TypeScript file, or by extracting a .d.ts type declaration file from your server code using tsc --declaration.
With that done, you can apply types to your client:
import { WorkerEntrypoint } from "cloudflare:workers";

// The interface that your server-side entrypoint implements.
// (This would probably be imported from a .d.ts file generated
// from your server code.)
declare class MyEntrypointType extends WorkerEntrypoint {
  sum(a: number, b: number): number;
}

// Define an interface Env specifying the bindings your client-side
// worker expects.
interface Env {
  MY_SERVICE: Service<MyEntrypointType>;
}

// Define the client worker's fetch handler with typed Env.
export default <ExportedHandler<Env>> {
  async fetch(req, env, ctx) {
    // Now env.MY_SERVICE is properly typed!
    const result = await env.MY_SERVICE.sum(1, 2);
    return new Response(result.toString());
  }
}
RPC to Durable Objects
Durable Objects allow you to create a “named” worker instance somewhere on the network that multiple other workers can then talk to, in order to coordinate between them. Each Durable Object also has its own private on-disk storage where it can store state long-term.
Previously, communications with a Durable Object had to take the form of HTTP requests and responses. With RPC, you can now just declare methods on your Durable Object class, and call them on the stub. One catch: to opt into RPC, you must declare your Durable Object class with extends DurableObject, like so:
import { DurableObject } from "cloudflare:workers";

export class Counter extends DurableObject {
  async increment() {
    // Increment our stored value and return it.
    let value = await this.ctx.storage.get("value");
    value = (value || 0) + 1;
    this.ctx.storage.put("value", value);
    return value;
  }
}
Now we can call it like:
let stub = env.COUNTER_NAMEPSACE.get(id);
let value = await stub.increment();
TypeScript is supported here too, by defining your binding with type DurableObjectNamespace<ServerType>:
When talking to a Durable Object, the object may be somewhere else in the world from the caller. RPCs must cross the network. This takes time: despite our best efforts, we still haven’t figured out how to make information travel faster than the speed of light.
When you have a complex RPC interface where one call returns an object on which you wish to make further method calls, it’s easy to end up with slow code that makes too many round trips over the network.
// Makes three round trips.
let foo = await stub.foo();
let baz = await foo.bar.baz();
let corge = await baz.qux[3].corge();
Workers RPC features a way to avoid this: If you know that a call will return a value containing a stub, and all you want to do with it is invoke a method on that stub, you can skip awaiting it:
// Same thing, only one round trip.
let foo = stub.foo();
let baz = foo.bar.baz();
let corge = await baz.qux[3].corge();
Whoa! How does this work?
RPC methods do not return normal promises. Instead, they return special RPC promises. These objects are “custom thenables“, which means you can use them in all the ways you’d use a regular Promise, like awaiting it or calling .then() on it.
But an RPC promise is more than just a thenable. It is also a proxy. Like an RPC stub, it has a wildcard property. You can use this to express speculative RPC calls on the eventual result, before it has actually resolved. These speculative calls will be sent to the server immediately, so that they can begin executing as soon as the first RPC has finished there, before the result has actually made its way back over the network to the client.
This feature is also known as “Promise Pipelining”. Although it isn’t explicitly a security feature, it is commonly provided by object-capability RPC systems like Cap’n Proto.
The future: Custom Bindings Marketplace?
For now, Service Bindings and Durable Objects only allow communication between Workers running on the same account. So, RPC can only be used to talk between your own Workers.
But we’d like to take it further.
We have previously explained why Workers environments contain live objects, also known as “bindings”. But today, only Cloudflare can add new binding types to the Workers platform – like Queues, KV, or D1. But what if anyone could invent their own binding type, and give it to other people?
Previously, we thought this would require creating a way to automatically load client libraries into the calling Workers. That seemed scary: it meant using someone’s binding would require trusting their code to run inside your isolate. With RPC, there’s no such trust. The binding only sees exactly what you explicitly pass to it. It cannot compromise the rest of your Worker.
Could Workers RPC provide the basis for a “bindings marketplace”, where people can offer rich JavaScript APIs to each other in an easy and secure way? We’re excited to explore and find out.
Try it now
Workers RPC is available today for all Workers users. To get started, check out the docs.
Browser Rendering API is now available to all paid Workers customers with improved session management
In May 2023, we announced the open beta program for the Browser Rendering API. Browser Rendering allows developers to programmatically control and interact with a headless browser instance and create automation flows for their applications and products.
At the same time, we launched a version of the Puppeteer library that works with Browser Rendering. With that, developers can use a familiar API on top of Cloudflare Workers to create all sorts of workflows, such as taking screenshots of pages or automatic software testing.
Today, we take Browser Rendering one step further, taking it out of beta and making it available to all paid Workers’ plans. Furthermore, we are enhancing our API and introducing a new feature that we’ve been discussing for a long time in the open beta community: session management.
Session Management
Session management allows developers to reuse previously opened browsers across Worker’s scripts. Reusing browser sessions has the advantage that you don’t need to instantiate a new browser for every request and every task, drastically increasing performance and lowering costs.
Before, to keep a browser instance alive and reuse it, you’d have to implement complex code using Durable Objects. Now, we’ve simplified that for you by keeping your browsers running in the background and extending the Puppeteer API with new session management methods that give you access to all of your running sessions, activity history, and active limits.
Observability is an essential part of any Cloudflare product. You can find detailed analytics and logs of your Browser Rendering usage in the dashboard under your account’s Worker & Pages section.
Browser Rendering is now available to all customers with a paid Workers plan. Each account is limited to running two new browsers per minute and two concurrent browsers at no cost during this period. Check our developers page to get started.
We are rolling out access to Cloudflare Snippets
Powerful, programmable, and free of charge, Snippets are the best way to perform complex HTTP request and response modifications on Cloudflare. What was once too advanced to achieve using Rules products is now possible with Snippets. Since the initial announcement during Developer Week 2022, the promise of extending out-of-the-box Rules functionality by writing simple JavaScript code is keeping the Cloudflare community excited.
During the first 3 months of 2024 alone, the amount of traffic going through Snippets increased over 7x, from an average of 2,200 requests per second in early January to more than 17,000 in March.
However, instead of opening the floodgates and letting millions of Cloudflare users in to test (and potentially break) Snippets in the most unexpected ways, we are going to pace ourselves and opt for a phased rollout, much like the newly released Gradual Rollouts for Workers.
In the next few weeks, 5% of Cloudflare users will start seeing “Snippets” under the Rules tab of the zone-level menu in their dashboard. If you happen to be part of the first 5%, snip into action and try out how fast and powerful Snippets are even for advanced use cases like dynamically changing the date in headers or A / B testing leveraging the `math.random` function. Whatever you use Snippets for, just keep one thing in mind: this is still an alpha, so please do not use Snippets for production traffic just yet.
Until then, keep your eyes out for the new Snippets tab in the Cloudflare dashboard and learn more how powerful and flexible Snippets are at the developer documentation in the meantime.
Coming soon: asynchronous revalidation with stale-while-revalidate
One of the features most requested by our customers is the asynchronous revalidation with stale-while-revalidate (SWR) cache directive, and we will be bringing this to you in the second half of 2024. This functionality will be available by design as part of our new CDN architecture that is being built using Rust with performance and memory safety at top of mind.
Currently, when a client requests a resource, such as a web page or an image, Cloudflare checks to see if the asset is in cache and provides a cached copy if available. If the file is not in the cache or has expired and become stale, Cloudflare connects to the origin server to check for a fresh version of the file and forwards this fresh version to the end user. This wait time adds latency to these requests and impacts performance.
Stale-while-revalidate is a cache directive that allows the expired or stale version of the asset to be served to the end user while simultaneously allowing Cloudflare to check the origin to see if there’s a fresher version of the resource available. If an updated version exists, the origin forwards it to Cloudflare, updating the cache in the process. This mechanism allows the client to receive a response quickly from the cache while ensuring that it always has access to the most up-to-date content. Stale-while-revalidate strikes a balance between serving content efficiently and ensuring its freshness, resulting in improved performance and a smoother user experience.
Customers who want to be part of our beta testers and “cache” in on the fun can register here, and we will let you know when the feature is ready for testing!
Coming on April 16, 2024: Workers for Platforms for our pay-as-you-go plan
Today, we’re excited to share that on April 16th, Workers for Platforms will be available to all developers through our new $25 pay-as-you-go plan!
Workers for Platforms is changing the way we build software – it gives you the ability to embed personalization and customization directly into your product. With Workers for Platforms, you can deploy custom code on behalf of your users or let your users directly deploy their own code to your platform, without you or your users having to manage any infrastructure. You can use Workers for Platforms with all the exciting announcements that have come out this Developer Week – it supports all the bindings that come with Workers (including Workers AI, D1 and Durable Objects) as well as Python Workers.
Here’s what some of our customers – ranging from enterprises to startups – are building on Workers for Platforms:
Shopify Oxygen is a hosting platform for their Remix-based eCommerce framework Hydrogen, and it’s built on Workers for Platforms! The Hydrogen/Oxygen combination gives Shopify merchants control over their buyer experience without the restrictions of generic storefront templates.
Grafbase is a data platform for developers to create a serverless GraphQL API that unifies data sources across a business under one endpoint. They use Workers for Platforms to give their developers the control and flexibility to deploy their own code written in JavaScript/TypeScript or WASM.
Triplit is an open-source database that syncs data between server and browser in real-time. It allows users to build low latency, real-time applications with features like relational querying, schema management and server-side storage built in. Their query and sync engine is built on top of Durable Objects, and they’re using Workers for Platforms to allow their customers to package custom Javascript alongside their Triplit DB instance.
Tools for observability and platform level controls
Workers for Platforms doesn’t just allow you to deploy Workers to your platform – we also know how important it is to have observability and control over your users’ Workers. We have a few solutions that help with this:
Custom Limits: Set CPU time or subrequest caps on your users’ Workers. Can be used to set limits in order to control your costs on Cloudflare and/or shape your own pricing and packaging model. For example, if you run a freemium model on your platform, you can lower the CPU time limit for customers on your free tier.
Tail Workers: Tail Worker events contain metadata about the Worker, console.log() messages, and capture any unhandled exceptions. They can be used to provide your developers with live logging in order to monitor for errors and troubleshoot in real time.
Outbound Workers: Get visibility into all outgoing requests from your users’ Workers. Outbound Workers sit between user Workers and the fetch() requests they make, so you get full visibility over the request before it’s sent out to the Internet.
Pricing
We wanted to make sure that Workers for Platforms was affordable for hobbyists, solo developers, and indie developers. Workers for Platforms is part of a new $25 pay-as-you-go plan, and it includes the following:
Included Amounts
Requests
20 million requests/month +$0.30 per additional million
CPU time
60 million CPU milliseconds/month +$0.02 per additional million CPU milliseconds
Scripts
1000 scripts +0.02 per additional script/month
Workers for Platforms will be available to purchase on April 16, 2024!
The Workers for Platforms will be available to purchase under the Workers for Platforms tab on the Cloudflare Dashboard on April 16, 2024.
2024’s Developer Week is all about production readiness. On Monday. April 1, we announced that D1, Queues, Hyperdrive, and Workers Analytics Engine are ready for production scale and generally available. On Tuesday, April 2, we announced the same about our inference platform, Workers AI. And we’re not nearly done yet.
However, production readiness isn’t just about the scale and reliability of the services you build with. You also need tools to make changes safely and reliably. You depend not just on what Cloudflare provides, but on being able to precisely control and tailor how Cloudflare behaves to the needs of your application.
Today we are announcing five updates that put more power in your hands – Gradual Deployments, source mapped stack traces in Tail Workers, a new Rate Limiting API, brand-new API SDKs, and updates to Durable Objects – each built with mission-critical production services in mind. We build our own products using Workers, including Access, R2, KV, Waiting Room, Vectorize, Queues, Stream, and more. We rely on each of these new features ourselves to ensure that we are production ready – and now we’re excited to bring them to everyone.
Gradually deploy changes to Workers and Durable Objects
Deploying a Worker is nearly instantaneous – a few seconds and your change is live everywhere.
When you reach production scale, each change you make carries greater risk, both in terms of volume and expectations. You need to meet your 99.99% availability SLA, or have an ambitious P90 latency SLO. A bad deployment that’s live for 100% of traffic for 45 seconds could mean millions of failed requests. A subtle code change could cause a thundering herd of retries to an overwhelmed backend, if rolled out all at once. These are the kinds of risks we consider and mitigate ourselves for our own services built on Workers.
The way to mitigate these risks is to deploy changes gradually – commonly called rolling deployments:
The current version of your application runs in production.
You deploy the new version of your application to production, but only route a small percentage of traffic to this new version, and wait for it to “soak” in production, monitoring for regressions and bugs. If something bad happens, you’ve caught it early at a small percentage (e.g. 1%) of traffic and can revert quickly.
You gradually increment the percentage of traffic until the new version receives 100%, at which point it is fully rolled out.
Today we’re opening up a first-class way to deploy code changes gradually to Workers and Durable Objects via the Cloudflare API, the Wrangler CLI, or the Workers dashboard. Gradual Deployments is entering open beta – you can use Gradual Deployments with any Cloudflare account that is on the Workers Free plan, and very soon you’ll be able to start using Gradual Deployments with Cloudflare accounts on the Workers Paid and Enterprise plans. You’ll see a banner on the Workers dashboard once your account has access.
When you have two versions of your Worker or Durable Object running concurrently in production, you almost certainly want to be able to filter your metrics, exceptions, and logs by version. This can help you spot production issues early, when the new version is only rolled out to a small percentage of traffic, or compare performance metrics when splitting traffic 50/50. We’ve also added observability at a version level across our platform:
You can filter analytics in the Workers dashboard and via the GraphQL Analytics API by version.
Workers Trace Events and Tail Worker events include the version ID of your Worker, along with optional version message and version tag fields.
When using wrangler tail to view live logs, you can view logs for a specific version.
You can access version ID, message, and tag from within your Worker’s code, by configuring the Version Metadata binding.
You may also want to make sure that each client or user only sees a consistent version of your Worker. We’ve added Version Affinity so that requests associated with a particular identifier (such as user, session, or any unique ID) are always handled by a consistent version of your Worker. Session Affinity, when used with Ruleset Engine, gives you full control over both the mechanism and identifier used to ensure “stickiness”.
Gradual Deployments is entering open beta. As we move towards GA, we’re working to support:
Version Overrides. Invoke a specific version of your Worker in order to test before it serves any production traffic. This will allow you to create Blue-Green Deployments.
Cloudflare Pages. Let the CI/CD system in Pages automatically progress the deployments on your behalf.
Automatic rollbacks. Roll back deployments automatically when the error rate spikes for a new version of your Worker.
We’re looking forward to hearing your feedback! Let us know what you think through this feedback form or reach out in our Developer Discord in the #workers-gradual-deployments-beta channel.
Source mapped stack traces in Tail Workers
Production readiness means tracking errors and exceptions, and trying to drive them down to zero. When an error occurs, the first thing you typically want to look at is the error’s stack trace – the specific functions that were called, in what order, from which line and file, and with what arguments.
Most JavaScript code – not just on Workers, but across platforms – is first bundled, often transpiled, and then minified before being deployed to production. This is done behind the scenes to create smaller bundles to optimize performance and convert from Typescript to JavaScript if needed.
If you’ve ever seen an exception return a stack trace like: /src/index.js:1:342,it means the error occurred on the 342nd character of your function’s minified code. This is clearly not very helpful for debugging.
Source maps solve this – they map compiled and minified code back to the original code that you wrote. Source maps are combined with the stack trace returned by the JavaScript runtime in order to present you with a human-readable stack trace. For example, the following stack trace shows that the Worker received an unexpected null value on line 30 of the down.ts file. This is a useful starting point for debugging, and you can move down the stack trace to understand the functions that were called that were set that resulted in the null value.
Unexpected input value: null
  at parseBytes (src/down.ts:30:8)
  at down_default (src/down.ts:10:19)
  at Object.fetch (src/index.ts:11:12)
When your Worker throws an uncaught exception, we fetch the source map and use it to map the stack trace of the exception back to lines of your Worker’s original source code.
Starting today, in open beta, you can upload source maps to Cloudflare when you deploy your Worker – get started by reading the docs. And starting on April 15th , the Workers runtime will start using source maps to deobfuscate stack traces. We’ll post a notification in the Cloudflare dashboard and post on our Cloudflare Developers X account when source mapped stack traces are available.
New Rate Limiting API in Workers
An API is only production ready if it has a sensible rate limit. And as you grow, so does the complexity and diversity of limits that you need to enforce in order to balance the needs of specific customers, protect the health of your service, or enforce and adjust limits in specific scenarios. Cloudflare’s own API has this challenge – each of our dozens of products, each with many API endpoints, may need to enforce different rate limits.
You’ve been able to configure Rate Limiting rules on Cloudflare since 2017. But until today, the only way to control this was in the Cloudflare dashboard or via the Cloudflare API. It hasn’t been possible to define behavior at runtime, or write code in a Worker that interacts directly with rate limits – you could only control whether a request is rate limited or not before it hits your Worker.
Today we’re introducing a new API, in open beta, that gives you direct access to rate limits from your Worker. It’s lightning fast, backed by memcached, and dead simple to add to your Worker. For example, the following configuration defines a rate limit of 100 requests within a 60-second period:
[[unsafe.bindings]]
name = "RATE_LIMITER"
type = "ratelimit"
namespace_id = "1001" # An identifier unique to your Cloudflare account

# Limit: the number of tokens allowed within a given period, in a single Cloudflare location
# Period: the duration of the period, in seconds. Must be either 60 or 10
simple = { limit = 100, period = 60 }
Then, in your Worker, you can call the limit method on the RATE_LIMITER binding, providing a key of your choosing. Given the configuration above, this code will return a HTTP 429 response status code once more than 100 requests to a specific path are made within a 60-second period:
export default {
  async fetch(request, env) {
    const { pathname } = new URL(request.url)

    const { success } = await env.RATE_LIMITER.limit({ key: pathname })
    if (!success) {
      return new Response(`429 Failure – rate limit exceeded for ${pathname}`, { status: 429 })
    }

    return new Response(`Success!`)
  }
}
Now that Workers can connect directly to a data store like memcached, what else could we provide? Counters? Locks? An in-memory cache? Rate limiting is the first of many primitives that we’re exploring providing in Workers that address questions we’ve gotten for years about where a temporary shared state that spans many Worker isolates should live. If you rely on putting state in the global scope of your Worker today, we’re working on better primitives that are purpose-built for specific use cases.
The Rate Limiting API in Workers is in open beta, and you can get started by reading the docs.
New auto-generated SDKs for Cloudflare’s API
Production readiness means going from making changes by clicking buttons in a dashboard to making changes programmatically, using an infrastructure-as-code approach like Terraform or Pulumi, or by making API requests directly, either on your own or via an SDK.
We’ve done that, and today we’re announcing new client SDKs for the Cloudflare API in three languages – Typescript, Python and Go – with more languages on the way.
Each SDK is generated automatically using Stainless API, based on the OpenAPI schemas that define the structure and capabilities of each of our API endpoints. This means that when we add any new functionality to the Cloudflare API, across any Cloudflare product, these API SDKs are automatically regenerated, and new versions are published, ensuring that they are correct and up-to-date.
You can install the SDKs by running one of the following commands:
// Typescript
npm install cloudflare

// Python
pip install --pre cloudflare

// Go
go get -u github.com/cloudflare/cloudflare-go/v2
If you use Terraform or Pulumi, under the hood, Cloudflare’s Terraform Provider currently uses the existing, non-automated Go SDK. When you run terraform apply, the Cloudflare Terraform Provider determines which API requests to make in what order, and executes these using the Go SDK.
The new, auto-generated Go SDK clears a path towards more comprehensive Terraform support for all Cloudflare products, providing a base set of tools that can be relied upon to be both correct and up-to-date with the latest API changes. We’re building towards a future where any time a product team at Cloudflare builds a new feature that is exposed via the Cloudflare API, it is automatically supported by the SDKs. Expect more updates on this throughout 2024.
Durable Object namespace analytics and WebSocket Hibernation GA
Many of our own products, including Waiting Room, R2, and Queues, as well as platforms like PartyKit, are built using Durable Objects. Deployed globally, including newly added support for Oceania, you can think of Durable Objects like singleton Workers that can provide a single point of coordination and persist state. They’re perfect for applications that need real-time user coordination, like interactive chat or collaborative editing. Take Atlassian’s word for it:
One of our new capabilities is Confluence whiteboards, which provides a freeform way to capture unstructured work like brainstorming and early planning before teams document it more formally. The team considered many options for real-time collaboration and ultimately decided to use Cloudflare’s Durable Objects. Durable Objects have proven to be a fantastic fit for this problem space, with a unique combination of functionalities that has allowed us to greatly simplify our infrastructure and easily scale to a large number of users. – Atlassian
We haven’t previously exposed associated analytical trends in the dashboard, making it hard to understand the usage patterns and error rates within a Durable Objects namespace unless you used the GraphQL Analytics API directly. The Durable Objects dashboard has now been revamped, letting you drill down into metrics, and go as deep as you need.
From day one, Durable Objects have supported WebSockets, allowing many clients to directly connect to a Durable Object to send and receive messages.
However, sometimes client applications open a WebSocket connection and then eventually stop doing…anything. Think about that tab you’ve had sitting open in your browser for the last 5 hours, but haven’t touched. If it uses WebSockets to send and receive messages, it effectively has a long-lived TCP connection that isn’t being used for anything. If this connection is to a Durable Object, the Durable Object must stay running, waiting for something to happen, consuming memory, and costing you money.
We first introduced WebSocket Hibernation to solve this problem, and today we’re announcing that this feature is out of beta and is Generally Available. With WebSocket Hibernation, you set an automatic response to be used while hibernating and serialize state such that it survives hibernation. This gives Cloudflare the inputs we need in order to maintain open WebSocket connections from clients while “hibernating” the Durable Object such that it is not actively running, and you are not billed for idle time. The result is that your state is always available in-memory when you actually need it, but isn’t unnecessarily kept around when it’s not. As long as your Durable Object is hibernating, even if there are active clients still connected over a WebSocket, you won’t be billed for duration.
In addition, we’ve heard developer feedback on the costs of incoming WebSocket messages to Durable Objects, which favor smaller, more frequent messages for real-time communication. Starting today incoming WebSocket messages will be billed at the equivalent of 1/20th of a request (as opposed to 1 message being the equivalent of 1 request as it has been up until now). Following a pricing example:
WebSocket Connection Requests
Incoming WebSocket Messages
Billed Requests
Request Billing
Before
10K
432M
432,010,000
$64.65
After
10K
432M
21,610,000
$3.09
Production ready, without production complexity
Becoming production ready on the last generation of cloud platforms meant slowing down how fast you shipped. It meant stitching together many disconnected tools or standing up whole teams to work on internal platforms. You had to retrofit your own productivity layers onto platforms that put up roadblocks.
The Cloudflare Developer Platform is grown up and production ready, and committed to being an integrated platform where products intuitively work together and where there aren’t 10 ways to do the same thing, with no need for a compatibility matrix to help understand what works together. Each of these updates shows this in action, integrating new functionality across products and parts of Cloudflare’s platform.
To that end, we want to hear from you about not only what you want to see next, but where you think we could be even simpler, or where you think our products could work better together. Tell us where you think we could do more – the Cloudflare Developers Discord is always open.
Pages has superpowers like these that Workers does not have, and vice versa. Today you have to choose upfront whether to build a Worker or a Pages project, even though the two products largely overlap. That’s why during 2023’s Developer Week, we started bringing both products together to give developers the benefit of the best of both worlds. And it’s why we announced that like Workers, Pages projects can now directly access bindings to Cloudflare services — using workerd under-the-hood — even when using the local development server provided by a full-stack framework like Astro, Next.js, Nuxt, Qwik, Remix, SolidStart, or SvelteKit. Today, we’re thrilled to be launching some new improvements to Pages that bring functionality previously restricted to Workers. Welcome to the stage: monorepos, wrangler.toml, new additions to Next.js support, and database integrations!
Pages now supports monorepos
Many development teams use monorepos – repositories that contain multiple apps, with each residing in its own subdirectory. This approach is extremely helpful when these apps share code.
Previously, the Pages CI/CD set-up limited users to one repo per project. To use a monorepo with Pages, you had to directly upload it on your own, using the Wrangler CLI. If you did this, you couldn’t use Pages’ integration with GitHub or Gitlab, or have Pages CI/CD handle builds and deployments. With Pages support for monorepos, development teams can trigger builds to their various projects with each push.
Manage builds and move fast You can now include and exclude specific paths to watch for in each of your projects to avoid unnecessary builds from commits to your repo.
Let’s say a monorepo contains 4 subdirectories – a marketing app, an ecommerce app, a design library, and a package. The marketing app depends on the design library, while the ecommerce app depends on the design library and the package.
Updates to the design library should rebuild and redeploy both applications, but an update to the marketing app shouldn’t rebuild and deploy the ecommerce app. However, by default, any push you make to my-monorepo triggers a build for both projects regardless of which apps were changed. Using the include/exclude build controls, you can specify paths to build and ignore for your project to help you track dependencies and build more efficiently.
Bring your own tools Already using tools like Turborepo, NX, and Lerna? No problem! You can also bring your favorite monorepo management tooling to Pages to help manage your dependencies quickly and efficiently.
Whatever your tooling and however you’re set up, check out our documentation to get started with your monorepo right out of the box.
Configure Pages projects with wrangler.toml
Today, we’re excited to announce that you can now configure Pages projects using wrangler.toml — the same configuration file format that is already used for configuring Workers.
Previously, Pages projects had to be configured exclusively in the dashboard. This forced you to context switch from your development environment any time you made a configuration change, like adding an environment variable or binding. It also separated configuration from code, making it harder to know things like what bindings are being used in your project. If you were developing as a team, all the users on your team had to have access to your account to make changes – even if they had access to make changes to the source code via your repo.
With wrangler.toml, you can:
Store your configuration file in source control. Keep your configuration in your repo alongside the rest of your code.
Edit your configuration via your code editor. Remove the need to switch back and forth between interfaces.
Write configuration that is shared across environments.Define bindings and environment variables for local, preview, and production in one file.
Ensure better access control. By using a configuration file in your repo, you can control who has access to make changes without giving access to your Cloudflare dashboard.
Migrate existing projects If you have an existing Pages project, we’ve added a new Wrangler CLI command that downloads your existing configuration and provides you with a valid wrangler.toml file.
Run this command, add the wrangler.toml file that it generates to your project’s root directory, and then when you deploy, your project will be configured based on this configuration file.
If you are already using wrangler.toml to define your local development configuration, you can continue doing so. By default, your existing wrangler.toml file will continue to only apply to local development. When you run `wrangler pages deploy`, Wrangler will show you the additional fields that you must add in order for your configuration to apply to production and preview environments. Add these fields to your wrangler.toml, and then when you deploy your changes, the configuration you’ve defined in wrangler.toml will be used by your Pages project.
Refer to the documentation for more information on exactly what’s supported and how to leverage wrangler.toml in your development workflows.
Integrate Pages projects with your favorite database
You can already connect to D1, Cloudflare’s serverless SQL database, directly from Pages projects. And you can connect directly to your existing PostgreSQL database using Hyperdrive. Today, we’re making it even easier for you to connect 3rd party databases to Pages with just a couple of clicks. Pages now integrates directly with Neon, PlanetScale, Supabase, Turso, Upstash, and Xata!
Simply navigate to your Pages project’s settings, select your database provider, and we’ll add environment variables with credentials needed to connect as well a secret with the API key from the provider for you automatically.
Not ready to ship to production yet? You can deploy your changes to Pages’ preview environment alongside your staging database and test your deployment with its unique preview URL.
What’s coming up for integrations? We’re just getting started with database integrations, with many more providers to come. In the future, we’re also looking to expand our integrations platform to include seamless set up when building other components of your app – think authentication and observability!
Want to bring your favorite tools to Cloudflare but don’t see the integration option? Want to build out your own integration?
Not only are we looking for user input on new integrations to add, but we’re also opening up the integrations platform to builders who want to submit their own products! We’ll be releasing step-by-step documentation and tooling to easily build and publish your own integration. If you’re interested in submitting your own integration, please fill out our integration intake form and we’ll be in touch!
Improved Next.js Support for Pages
With 30 minor and patch releases since the 1.0 launch of next-on-pages during Dev Week 2023, our Next.js integration has been continuously maturing and keeping up with the evolution of Next.js. In addition to performance improvements, and compatibility and bug fixes, we released three significant improvements.
First, the ESLint plugin eslint-plugin-next-on-pages is a great way to catch and fix compatibility issues as you are writing your code before you build and deploy applications. The plugin contains several rules for the most common coding mistakes we see developers make, with more being added as we identify problematic scenarios.
Another noteworthy change is the addition of getRequestContext() APIs, which provides you with access to Cloudflare-specific resources and metadata about the request currently being processed by your application, allowing for example you to take client’s location or browser preferences into account when generating a response.
Last but not least, as we just shared in a dedicated post, we have completely overhauled the local development workflow for Next.js as well as other full-stack frameworks. Thanks to the new setupDevPlatform() API, you can now use the default development server `next dev`, with support for instant edit & refresh experience, while also using D1, R2, KV and other resources provided by the Cloudflare development platform. Want to take it for a quick spin? Use C3 to scaffold a new Next.js application with just one command.
What’s next for the convergence of Workers and Pages?
While today’s launch represents just a few of the many upcoming additions to converge Pages and Workers, we also wanted to share a few milestones that are on the horizon, planned later in 2024
Pages features coming soon to Workers
Workers CI/CD. Later this year, we plan to bring the CI/CD system from Cloudflare Pages to Cloudflare Workers. Connect your repositories to Cloudflare and trigger builds for your Workers with every commit.
Serve static assets from Workers. You will be able to deploy and serve static assets as part of Workers – just like you can with Pages today – and build Workers using full-stack frameworks! This will also extend to Workers for Platforms, allowing you to build platforms that let your customers deploy complete, full-stack applications that serve both dynamic and static assets.
Workers preview URLs. Preview versions of your Workers with every change and share a unique URL with your team for testing.
Workers features coming soon to Pages
Add Tail Workers to Pages projects. Get observability into your Pages Functions by capturing console.log() messages, unhandled exceptions, and request metadata, and then forward the information to external destinations.
Workers Trace Events Logpush. Push your Pages Functions logs to supported destinations like R2, Datadog, or any HTTP destination for long term storage, auditing, and compliance.
Gradual Deployments. Gradually deploy new versions of your Pages Function to reduce risk when making changes to critical applications.
You might also notice that the Pages and Workers interfaces in the Cloudflare Dash will begin to look more similar through the rest of this year. These changes aren’t just superficial, or us porting over functionality from one product to another. Under-the-hood, we are unifying the way that Workers and Pages projects are composed and then deployed to our network, ensuring that as we add new products and features, they can work with both Pages and Workers on day one.
In the meantime, bring your monorepo, a wrangler.toml, and your favorite databases to Pages and let’s rock! Be sure to show off what you’ve built in the Cloudflare Developer Discord or by giving us a shout at @CloudflareDev.
Data is fundamental to any real-world application: the database storing your user data and inventory, the analytics tracking sales events and/or error rates, the object storage with your web assets and/or the Parquet files driving your data science team, and the vector database enabling semantic search or AI-powered recommendations for your users.
When we first announced Workers back in 2017, and then Workers KV, Cloudflare R2, and D1, it was obvious that the next big challenge to solve for developers would be in making it easier to ingest, store, and query the data needed to build scalable, full-stack applications.
To that end, as part of our quest to make building stateful, distributed-by-default applications even easier, we’re launching our new Event Notifications service; a preview of our upcoming streaming ingestion product, Pipelines; and a sneak peek into our take on durable execution, Workflows.
Event-based architectures
When you’re writing data — whether that’s new data, changing existing data, or deleting old data — you often want to trigger other, asynchronous work to run in response. That could be processing user-driven uploads, updating search indexes as the underlying data changes, or removing associated rows in your SQL database when content is removed.
In order to make these event-driven workflows far easier to build across Cloudflare, we’re launching the first step towards a wider Event Notifications platform across Cloudflare, starting with notifications support in R2.
You can read more in the deep-dive on Event Notifications for R2, but in a nutshell: you can configure changes to content in any R2 bucket to write directly to a Queue, allowing you to reliably consume those events in a Worker or to pull from compute in a legacy cloud.
Event Notifications for R2 are just the beginning, though. There are many kinds of events you might want to trigger as a developer — these are just some of the event types we’re planning to support:
Changes (writes) to key-value pairs in your Workers KV namespaces.
Updates to your D1 databases, including changed rows or triggers.
Consuming event notifications from a single Worker is just one approach, though. As you start to consume events, you may want to trigger multi-step workflows that execute reliably, resume from errors or exceptions, and ensure that previous steps aren’t duplicated or repeated unnecessarily. An event notification framework turns out to be just the thing needed to drive a workflow engine that executes durably…
Making it even easier to ingest data
When we launched Cloudflare R2, our object storage service, we knew that supporting the de facto-standard S3 API was critical in order to allow developers to bring the tooling and services they already had over to R2. But the S3 API is designed to be simple: at its core, it provides APIs for upload, download, multipart and metadata operations, and many tools don’t support the S3 API.
What if you want to batch clickstream data from your web services so that it’s efficient (and cost-effective) to query by your analytics team? Or partition data by customer ID, merchant ID, or locale within a structured data format like JSON?
Well, we want to help solve this problem too, and so we’re announcing Pipelines, an upcoming streaming ingestion service designed to ingest data at scale, aggregate it, and write it directly to R2, without you having to manage infrastructure, partitions, runners, or worry about durability.
With Pipelines, creating a globally scalable ingestion endpoint that can ingest tens-of-thousands of events per second doesn’t require any code:
$ wrangler pipelines create clickstream-ingest-prod --batch-size="1MB" --batch-timeout-secs=120 --batch-on-json-key=".merchantId" --destination-bucket="prod-cs-data"

✅ Successfully created new pipeline "clickstream-ingest-prod"
📥 Created endpoints:
➡ HTTPS: https://d458dbe698b8eef41837f941d73bc5b3.pipelines.cloudflarestorage.com/clickstream-ingest-prod
➡ WebSocket: wss://d458dbe698b8eef41837f941d73bc5b3.pipelines.cloudflarestorage.com:8443/clickstream-ingest-prod
➡ Kafka: d458dbe698b8eef41837f941d73bc5b3.pipelines.cloudflarestorage.com:9092 (topic: clickstream-ingest-prod)
As you can see here, we’re already thinking about how to make Pipelines protocol-agnostic: write from a HTTP client, stream events over a WebSocket, and/or redirect your existing Kafka producer (and stop having to manage and scale Kafka) directly to Pipelines.
But that’s just the beginning of our vision here. Scalable ingestion and simple batching is one thing, but what about if you have more complex needs? Well, we have a massively scalable compute platform (Cloudflare Workers) that can help address this too.
The code below is just an initial exploration for how we’re thinking about an API for running transforms over streaming data. If you’re aware of projects like Apache Beam or Flink, this programming model might even look familiar:
export default {
   // Pipeline handler is invoked when batch criteria are met
   async pipeline(stream: StreamPipeline, env: Env, ctx: ExecutionContext): Promise<StreamingPipeline> {
      // ...
      return stream
         // Type: transform(label: string, transformFunc: TransformFunction): Promise<StreamPipeline>
         // Each transform has a label that is used in metrics to provide
    // per-transform observability and debugging
         .transform("human readable label", (events: Array<StreamEvent>) => {
            return events.map((e) => ...)
         })
         .transform("another transform", (events: Array<StreamEvent>) => {
            return events.map((e) => ...)
         })
         .writeToR2({
            format: "json",
            bucket: "MY_BUCKET_NAME",
            prefix: somePrefix,
            batchSize: "10MB"
         })
   }
}
Specifically:
The Worker describes a pipeline of transformations (mapping, reducing, filtering) that operates over each subset of events (records)
You can call out to other services — including D1 or KV — in order to synchronously or asynchronously hydrate data or lookup values during your stream processing
We take care of scaling horizontally based on records-per-second and/or any concurrency settings you configure based on processing latency requirements.
We’ll be bringing Pipelines into open beta later in 2024, and it will initially launch with support for HTTP ingestion and R2 as a destination (sink), but we’re already thinking bigger.
We’ll be sharing more as Pipelines gets closer to release. In the meantime, you can register your interest and share your use-case, and we’ll reach out when Pipelines reaches open beta.
Durable Execution
If the term “Durable Execution” is new to you, don’t worry: the term comes from the desire to run applications that can resume execution from where they left off, even if the underlying host or compute fails (where the “durable” part comes from).
As we’ve continued to build out our data and AI platforms, we’ve been acutely aware that developers need ways to create reliable, repeatable workflows that operate over that data, turn unstructured data into structured data, trigger on fresh data (or periodically), and automatically retry, restart, and export metrics for each step along the way. The industry calls this Durable Execution: we’re just calling it Workflows.
What makes Workflows different from other takes on Durable Execution is that we provide the underlying compute as part of the platform. You don’t have to bring-your-own compute, or worry about scaling it or provisioning it in the right locations. Workflows runs on top of Cloudflare Workers – you write the workflow, and we take care of the rest.
Here’s an early example of writing a Workflow that generates text embeddings using Workers AI and stores them (ready to query) in Vectorize as new content is written to (or updated within) R2.
Each Workflow run is triggered by an Event Notification consumed from a Queue, but could also be triggered by a HTTP request, another Worker, or even scheduled on a timer.
Individual steps within the Workflow allow us to define individually retriable units of work: in this case, we’re reading the new objects from R2, creating text embeddings using Workers AI, and then inserting.
State is durably persisted between steps: each step can emit state, and Workflows will automatically persist that so that any underlying failures, uncaught exceptions or network retries can resume execution from the last successful step.
Every call to step() automatically emits metrics associated with the unique Workflow run, making it easier to debug within each step and/or break down your application into its smallest units of execution, without having to worry about observability.
Step-by-step, it looks like this:
Transforming this series of steps into real code, here’s what this would look like with Workflows:
import { Ai } from "@cloudflare/ai";
import { Workflow } from "cloudflare:workers";

export interface Env {
  R2: R2Bucket;
  AI: any;
  VECTOR_INDEX: VectorizeIndex;
}

export default class extends Workflow {
  async run(event: Event) {
    const ai = new Ai(this.env.AI);

    // List of keys to fetch from our incoming event notification
    const keysToFetch = event.messages.map((val) => {
      return val.object.key;
    });

    // The return value of each step is stored (the "durable" part
    // of "durable execution")
    // This ensures that state can be persisted between steps, reducing
    // the need to recompute results ($$, time) should subsequent
    // steps fail.
    const inputs = await this.ctx.run(
      // Each step has a user-defined label
      // Metrics are emitted as each step runs (to success or failure)
// with this label attached and available within per-Workflow
// analytics in near-real-time.
"read objects from R2", async () => {
      const objects = [];

      for (const key of keysToFetch) {
        const object = await this.env.R2.get(key);
        objects.push(await object.text());
      }

      return objects;
    });


    // Persist the output of this step.
    const embeddings = await this.ctx.run(
      "generate embeddings",
      async () => {
        const { data } = await ai.run("@cf/baai/bge-small-en-v1.5", {
          text: inputs,
        });

        if (data.length) {
          return data;
        } else {
          // Uncaught exceptions trigger an automatic retry of the step
          // Retries and timeouts have sane defaults and can be overridden
    // per step
          throw new Error("Failed to generate embeddings");
        }
      },
      {
        retries: {
          limit: 5,
          delayMs: 1000,
          backoff: "exponential",
        },
      }
    );

    await this.ctx.run("insert vectors", async () => {
      const vectors = [];

      keysToFetch.forEach((key, index) => {
        vectors.push({
          id: crypto.randomUUID(),
          // Our embeddings from the previous step
          values: embeddings[index].values,
          // The path to each R2 object to map back to during
 	    // vector search
          metadata: { r2Path: key },
        });
      });

      return this.env.VECTOR_INDEX.upsert();
    });
  }
}
This is just one example of what a Workflow can do. The ability to durably execute an application, modeled as a series of steps, applies to a wide number of domains. You can apply this model of execution to a number of use-cases, including:
Deploying software: each step can define a build step and subsequent health check, gating further progress until your deployment meets your criteria for “healthy”.
Post-processing user data: triggering a workflow based on user uploads (e.g. to Cloudflare R2) that then subsequently parses that data asynchronously, redacts PII or sensitive data, writes the sanitized output, and triggers a notification via email, webhook, or mobile push.
Payment and batch workflows: aggregating raw customer usage data on a periodic schedule by querying your data warehouse (or Workers Analytics Engine), triggering usage or spend alerts, and/or generating PDF invoices.
Each of these use cases model tasks that you want to run to completion, minimize redundant retries by persisting intermediate state, and (importantly) easily observe success and failure.
We’ll be sharing more about Workflows during the second quarter of 2024 as we work towards an open (public!) beta. This includes how we’re thinking about idempotency and interactions with our storage, per-instance observability and metrics, local development, and templates to bootstrap common workflows.
Putting it together
We’ve often thought of Cloudflare’s own network as one massively scalable parallel data processing cluster: data centers in 310+ cities, with the ability to run compute close to users and/or close to data, keep it within the bounds of regulatory or compliance requirements, and most importantly, use our massive scale to enable our customers to scale as well.
Recapping, a fully-fledged data platform needs to enable three things:
Ingesting data: getting data into the platform (in the right format, from the right sources)
Storing data: securely, reliably, and durably.
Querying data: understanding and extracting insights from the data, and/or transforming it for use by other tools.
When we launched R2 we tackled the second part, but knew that we’d need to follow up with the first and third parts in order to make it easier for developers to get data in and make use of it.
If we look at how we can build a system that helps us solve each of these three parts together with Pipelines, Event Notifications, R2, and Workflows, we end up with an architecture that resembles this:
Specifically, we have Pipelines (1) scaling out to ingest data, batch it, filter it, and then durably store it in R2 (2) in a format that’s ready and optimized for querying. Workflows, ClickHouse, Databricks, or the query engine of your choice can then query (3) that data as soon as it’s ready — with “ready” being automatically triggered by an Event Notification as soon as the data is ingested and written to R2.
There’s no need to poll, no need to batch after the fact, no need to have your query engine slow down on data that wasn’t pre-aggregated or filtered, and no need to manage and scale infrastructure in order to keep up with load or data jurisdiction requirements. Create a Pipeline, write your data directly to R2, and query directly from it.
If you’re also looking at this and wondering about the costs of moving this data around, then we’re holding to one important principle: zero egress fees across all of our data products. Just as we set the stage for this with our R2 object storage, we intend to apply this to every data product we’re building, Pipelines included.
Start Building
We’ve shared a lot of what we’re building so that developers have an opportunity to provide feedback (including via our Developer Discord), share use-cases, and think about how to build their next application on Cloudflare.
Delivering great user experiences with a global user base can be challenging. While serving requests quickly when you start out in a local market is straightforward, doing so for a global audience is much more difficult. Why? Even under optimal conditions, you cannot be faster than the speed of light, which brings single data center solutions to their performance limits.
In this post, we will cover how Picsart improved the performance of one of its most critical services by moving from a centralized architecture to a globally distributed service built on Cloudflare. Our serverless compute platform, Workers, distributed throughout 310+ cities around the world, and our globally distributed Workers KV storage allowed them to improve their performance significantly and drive real business impact.
Success driven by data-driven insights
Picsart is one of the world’s largest digital creation platforms and a long-standing Cloudflare partner. At its core, an advanced tech stack powers its comprehensive features, including AI-driven photo and video editing tools and community-driven content sharing. With its infrastructure spanning across multiple cloud environments and on-prem deployments, Picsart is engineered to handle billions of daily requests from its huge mobile and web user base and API integrations. For over a decade, Cloudflare has been integral to Picsart, providing support for performant content delivery and securing its digital ecosystem.
Similar to many other tech giants, Picsart approaches product development in a data-driven way. At the core of the innovation is Picsart’s remote configuration and experimentation platform, which enables product managers, UX researchers, and others to segment their user base into different test groups. These test groups might get to see slightly different implementations of features or designs of the Picsart app. Users might also get early access to experimental features or see different in-app promotions. In combination with constant monitoring of relevant KPIs, this allows for informed product decisions based on user preference and business impact.
On each app start, the client device sends a request to the remote configuration service for the latest setup tailored to the user’s session. The assignment of experiments relies on factors like the operating system and previous sessions, making each request unique and uncachable. Picsart’s app showcases extensive remote configuration capabilities, enabling adjustments to nearly every element. This results in a response containing a 1.5 MB configuration file for mobile clients. While the long-term solution is to reduce the file size, which has grown over time as more teams adopted the powerful service, this is not possible in the near or mid-term as it requires a major rewrite of all clients.
This setup request is blocking in the “hot path” during app start, as the results of this request will decide how the app itself looks and behaves. Hence, performance is critical. To ensure users are not waiting for too long, Picsart apps will wait for 1500ms on mobile for the request to complete – if it does not, the user will not be assigned a test group and the app will fallback to default settings.
The clock is ticking
While a 1500ms round trip time seems like a sufficiently large time budget, the data suggested otherwise. Before the improvements were implemented, a staggering 50% of devices could not complete the requests in time. How come? In these 1.5 seconds the following steps need to complete:
The request must travel from the users’ devices to the centralized backend servers
The server processes the request based on dozens of user attributes provided in the request and thousands of defined remote configuration variations, running experiments, and segments metadata. Using all the info, the server selects the right variation of each remote setting entry and builds the response payload.
The response must travel from the centralized backend servers to the user devices.
Looking at the data, it was clear to the Picsart team that their backend service was already well-optimized, taking only 30 milliseconds, a tiny fraction of the available time budget, to process each of the billions of monthly requests. The bulk of the request time came from network latency. Especially with mobile devices, last mile performance can be very volatile, eating away a significant amount of the available time budget. Not only that, but the data was clear: users closer to the origin server had a much higher chance of making the round trip in time versus users out of region. It quickly became obvious that Picsart, fueled by its global success, had outgrown a single-region setup.
To the drawing board
A solution that comes to mind would be to replicate the existing cloud infrastructure in multiple regions and use global load balancing to minimize the distance a request needs to travel. However, this introduces significant overhead and cost. On the infrastructure side, it is not only the additional compute instances and database clusters that incur cost, but also cross-region data transfer to keep data in sync. Moreover, technical teams would need to operate and monitor infrastructure in multiple regions, which can add a lot to the complexity and cognitive load, leading to decreased development velocity and productivity loss.
Workers and Workers KV seemed like the ideal solution. Both compute and data are globally distributed in 310+ locations around the world, resulting in a shorter distance between end users and the experimentation service. Not only that, but Cloudflare’s global-by-default approach allows for deployment with minimal overhead, and in contrast to other considered solutions, no additional fees to distribute the data around the globe.
No race without a clock
The objective for the refactor of the experimentation service was to increase the share of devices that successfully receive experimentation configuration within the set time budget.
But how to measure success? While synthetic testing can be useful in many situations, Picsart opted to come up with another clever solution:
During development, the Picsart engineers had already added a testing endpoint to the web and mobile versions of their app that sends a duplicate request to the new endpoint, discarding the response and swallowing all potential errors. This allows them to collect timing data based on real-user metrics without impacting the app’s performance and reliability.
A simplified version of this pattern for a web client could look like this:
// API endpoint URLs
const prodUrl = 'https://prod.example.com/';
const devUrl = 'https://new.example.com/';

// Function to collect metrics
const collectMetrics = (duration) => {
    console.log('Request duration:', duration);
    // …
};

// Function to fetch data from an endpoint and call collectMetrics
const fetchData = async (url, options) => {
    const startTime = performance.now();

    try {
        const response = await fetch(url, options);
        const endTime = performance.now();
        const duration = endTime - startTime;
        collectMetrics(duration);
        return await response.json();
    } catch (error) {
        console.error('Error fetching data:', error);
    }
};

// Fetching data from both endpoints
async function fetchDataFromBothEndpoints() {
    try {
        const result1 = await fetchData(prodUrl, { method: 'POST', ... });
        console.log('Result from endpoint 1:', result1);

        // Fetching data from the second endpoint without awaiting its completion
        fetchData(devUrl, { method: 'POST', ... });
    } catch (error) {
        console.error('Error fetching data from both endpoints:', error);
    }
}

fetchDataFromBothEndpoints();
Using existing data analytics tools, Picsart was able to analyze the performance of the new services from day one, starting with a dummy endpoint and a ‘hello world’ response. And with that a v0 was created that did not have the correct logic just yet, but simulated reading multiple values from KV and returning a response of a realistic size back to the end user.
The need for a do-over
In the initial phase, outcomes fell short of expectations. Surprisingly, requests were slower despite the service’s proximity to end users. What caused this setback? Subsequent investigation unveiled multiple culprits and design patterns in need for optimization.
Data segmentation
The previous, stateful solution operated on a single massive “blob” of data exceeding 100MB in value. Loading this into memory incurred a few seconds of initial startup time, but once the VM completed the task, request handling was fast, benefiting from the readily available data in memory.
However, this approach doesn’t seamlessly transition to the serverless realm. Unlike long-running VMs, Worker isolates have short lifespans. Repeatedly parsing large JSON objects led to prolonged compute durations. Simply parsing four KV entries of 25MB each (KV maximum value size is 25MB) on each request was not a feasible option.
The Picsart team went back to solution design and embarked on a journey to optimize their system’s execution time, resulting in a series of impactful improvements.
The fundamental insight that guided the solution was the unnecessary overhead that was involved in loading and parsing data irrelevant to the user’s specific context. The 100MB configuration file contained configurations for all platforms and locations worldwide – a setup that was far from efficient in a globally distributed, serverless compute environment. For instance, when processing requests from users in the United States, there was no need to fetch configurations targeted for users in other countries, or for different platforms.
To address this inefficiency, the Picsart team stored the configuration of each platform and country in separate KV records. This targeted strategy meant that for a request originating from a US user on an Android device, our system would only fetch and parse the KV record specific to Android users in the US, thereby excluding all irrelevant data. This resulted in approximately 600 KV records, each with a maximum size of 10MB. While this leads to data duplication on the KV storage side, it decreases the amount of data that needs to be parsed upon request. As Cloudflare operates in over 120 countries around the world, only a subset of records were needed in each location. Hence, the increase in cardinality had minimal impact on KV cache performance, as demonstrated by more than 99.5% of KV reads being served from local cache.
Key
Size
settings_part1.json
25MB
settings_part2.json
25MB
…
….
Before (simplified)
Key
Size
com.picsart.studio_apple_us.json
6.1MB
com.picsart.studio_apple_de.json
6.1MB
com.picsart.studio_android_us.json
5.9MB
…
…
After (simplified)
This approach was a significant move for Picsart as they transitioned from a regional cloud setup to Cloudflare’s globally distributed connectivity cloud. By serving data from close proximity to end user locations, they were able to combat the high network latency from their previous setup. This strategy radically transformed the data-handling process. which unlocked two major benefits:
Performance Gains: By ensuring that only the relevant subset of data is fetched and parsed based on the user’s platform and geographical location, wall time and compute resources required for these operations could be significantly reduced.
Scalability and Flexibility: the granular segmentation of data enables effortless scaling of the service for new features or regional content. Adding support for new applications now only requires inserting new, standalone KV records in contrast to the previous solution where this would require increasing the size of the single record.
Immutable updates
Now that changes to the configuration were segmented by app, country, and platform, this also allowed for individual updates of the configuration in KV. KV storage showcases its best performance when records are updated infrequently but read very often. This pattern leverages KV’s fundamental design to cache values at edge locations upon reads, ensuring that subsequent queries for the same record are swiftly served by local caches rather than requiring a trip back to KV’s centralized data centers. This architecture is fundamental for minimizing latency and maximizing the speed of data retrieval across a globally distributed platform.
A crucial requirement for Picsart’s experimentation system was the ability to propagate updates of remote configuration values immediately. Updating existing records would require very short cache TTLs and even the minimum KV cache TTL of 60 seconds was considered unacceptable for the dynamic nature of the feature flagging. Moreover, setting short TTLs also impacts the cache hit ratio and the overall KV performance, specifically in regions with low traffic.
To reconcile the need for both rapid updates and efficient caching, Picsart adopted an innovative approach: making KV records immutable. Instead of modifying existing records, they opted to create new records with each configuration change. By appending the content hash to the KV key and writing new records after each update, Picsart ensured that each record was unique and immutable. This allowed them to leverage higher cache TTLs, as these records would never be updated.
Key
Size
com.picsart.studio_apple_us.json
60s
…
….
Before (simplified)
Key
Size
com.picsart.studio_apple_us_b58b59.json
86400s
com.picsart.studio_apple_us_273678.json
86400s
–
…
After (simplified)
There was a catch, though. The service must now keep track of the correct KV keys to use. The Picsart team addressed this challenge by storing references to the latest KV keys in the environment variables of the Worker.
Each configuration change triggers a new KV pair to be written and the services’ environment variables to be updated. As global Workers deployments take mere seconds, changes to the experimentation and configuration data are near-instantaneously globally available.
JSON serialization & alternatives
Following the previous improvements, the Picsart team made another significant discovery: only a small fraction of configuration data is needed to assign the experiments, while the remaining majority of the data comprises JSON values for the remote configuration payloads. While the service must deliver the latter in the response, the data is not required during the initial processing phase.
The initial implementation used KV’s get() method to retrieve the configuration data with the parameter type=json, which converts the KV value to an object. This process is very compute-intensive compared to using the get() method with parameter type= text, which simply returns the value as a string. In the context of Picsart’s data, the bulk of the CPU cycles were wasted on serializing JSON data that is not needed to perform the required business logic.
What if the data structure and code could be changed in such a way that only the data needed to assign experiments was parsed as JSON, while the configuration values were treated as text? Picsart went ahead with a new approach: splitting the KV records into two, creating a small 300KB record for the metadata, which can be quickly parsed to an object, and a 9.7MB record of configuration values. The extracted configuration values are delimited by newline characters. The respective line number is used as reference in the metadata entry, so that the respective configuration value for an experiment can be merged back into the payload response later.
After calculating the experiments and selecting the correct variants based solely on the small metadata entry, the service constructs a JSON string for the response containing placeholders for the actual values that reference the corresponding line numbers in the separate text file. To finalize the response, the server replaces the placeholders with the corresponding serialized JSON strings from the text file. This approach circumvents the need for parsing and re-serializing large JSON objects and helps to avoid a significant computational overhead.
Note that the process of parsing the metadata JSON and determining the correct experiments as well as the loading of the large file with configuration values are executed in parallel, saving additional milliseconds.
By minimizing the size of the JSON data that needed to be parsed and leveraging a more efficient method for constructing the final response, the Picsart team managed to not only reduce the response times but also optimize the compute resource usage. This approach reflects a broader principle applicable across the tech industry: that efficiency, particularly in serverless architectures, can often be dramatically improved by rethinking data structure and utilization.
Getting a head start
The changes on the server-side, moving from a single region setup to Cloudflare’s global architecture, paid off massively. Median response times globally dropped by more than 1 second, which was already a huge improvement for the team. However, in looking at the new data, two more paths for client-side optimizations were found.
As the web and mobile app would call the service at startup, most of the time no active connections to the servers were alive and establishing that connection at request time costs valuable milliseconds.
For the web version, setting a pre-connect header on initial page load showed a positive impact. For the mobile app version, the Picsart team took it a step further. Investigation showed that before the connection could be established, three modules had to complete initialization: the error tracker, the HTTP client, and the SDK. Reordering of the modules to initialize the HTTP client first allowed for connection establishment in parallel to the initialization of the SDK and error tracker, again saving time. This resulted in another 200ms improvement for end users.
Setting a new personal best
The day had come and it was time for the phased rollout, web first and the mobile apps second. With suspense, the team looked at the dashboards, and were pleasantly surprised. The rollout was successful and billions of requests were handled with ease.
Share of successfully delivered experiments
The result? The Picsart apps are loading faster than ever for millions of users worldwide, while the share of successfully delivered experiments increased from 50% to 85%. Median response time dropped from 1500 ms to 280 ms. The response time dropped to 70 ms on the web since the response size is smaller compared to mobile. This translates to a real business impact for Picsart as they can now deliver more personalized and data-driven experiences to even more of their users.
A bright future ahead
Picsart is already thinking of the next generation of experimentation. To integrate with Cloudflare even further, the plan is to use Durable Objects to store hundreds of millions of user data records in a decentralized fashion, enabling even more powerful experiments without impacting performance. This is possible thanks to Durable Objects’ underlying architecture that stores the user data in-region, close to the respective end user device.
Beyond that, Picsart’s experimentation team is also planning to onboard external B2B customers to their experimentation platform as Cloudflare’s developer platform provides them with the scale and global network to handle more traffic and data with ease.
Get started yourself
If you’re also working on or with an application that would benefit from Cloudflare’s speed and scale, check out our developer documentation and tutorials, and join our developer Discord to get community support and inspiration.
Inference from fine-tuned LLMs with LoRAs is now in open beta
Today, we’re excited to announce that you can now run fine-tuned inference with LoRAs on Workers AI. This feature is in open beta and available for pre-trained LoRA adapters to be used with Mistral, Gemma, or Llama 2, with some limitations. Take a look at our product announcements blog post to get a high-level overview of our Bring Your Own (BYO) LoRAs feature.
In this post, we’ll do a deep dive into what fine-tuning and LoRAs are, show you how to use it on our Workers AI platform, and then delve into the technical details of how we implemented it on our platform.
What is fine-tuning?
Fine-tuning is a general term for modifying an AI model by continuing to train it with additional data. The goal of fine-tuning is to increase the probability that a generation is similar to your dataset. Training a model from scratch is not practical for many use cases given how expensive and time consuming they can be to train. By fine-tuning an existing pre-trained model, you benefit from its capabilities while also accomplishing your desired task. Low-Rank Adaptation (LoRA) is a specific fine-tuning method that can be applied to various model architectures, not just LLMs. It is common that the pre-trained model weights are directly modified or fused with additional fine-tune weights in traditional fine-tuning methods. LoRA, on the other hand, allows for the fine-tune weights and pre-trained model to remain separate, and for the pre-trained model to remain unchanged. The end result is that you can train models to be more accurate at specific tasks, such as generating code, having a specific personality, or generating images in a specific style. You can even fine-tune an existing LLM to understand additional information about a specific topic.
The approach of maintaining the original base model weights means that you can create new fine-tune weights with relatively little compute. You can take advantage of existing foundational models (such as Llama, Mistral, and Gemma), and adapt them for your needs.
How does fine-tuning work?
To better understand fine-tuning and why LoRA is so effective, we have to take a step back to understand how AI models work. AI models (like LLMs) are neural networks that are trained through deep learning techniques. In neural networks, there are a set of parameters that act as a mathematical representation of the model’s domain knowledge, made up of weights and biases – in simple terms, numbers. These parameters are usually represented as large matrices of numbers. The more parameters a model has, the larger the model is, so when you see models like llama-2-7b, you can read “7b” and know that the model has 7 billion parameters.
A model’s parameters define its behavior. When you train a model from scratch, these parameters usually start off as random numbers. As you train the model on a dataset, these parameters get adjusted bit-by-bit until the model reflects the dataset and exhibits the right behavior. Some parameters will be more important than others, so we apply a weight and use it to show more or less importance. Weights play a crucial role in the model’s ability to capture patterns and relationships in the data it is trained on.
Traditional fine-tuning will adjust all the parameters in the trained model with a new set of weights. As such, a fine-tuned model requires us to serve the same amount of parameters as the original model, which means it can take a lot of time and compute to train and run inference for a fully fine-tuned model. On top of that, new state-of-the-art models, or versions of existing models, are regularly released, meaning that fully fine-tuned models can become costly to train, maintain, and store.
LoRA is an efficient method of fine-tuning
In the simplest terms, LoRA avoids adjusting parameters in a pre-trained model and instead allows us to apply a small number of additional parameters. These additional parameters are applied temporarily to the base model to effectively control model behavior. Relative to traditional fine-tuning methods it takes a lot less time and compute to train these additional parameters, which are referred to as a LoRA adapter. After training, we package up the LoRA adapter as a separate model file that can then plug in to the base model it was trained from. A fully fine-tuned model can be tens of gigabytes in size, while these adapters are usually just a few megabytes. This makes it a lot easier to distribute, and serving fine-tuned inference with LoRA only adds ms of latency to total inference time.
If you’re curious to understand why LoRA is so effective, buckle up — we first have to go through a brief lesson on linear algebra. If that’s not a term you’ve thought about since university, don’t worry, we’ll walk you through it.
Show me the math
With traditional fine-tuning, we can take the weights of a model (W0) and tweak them to output a new set of weights — so the difference between the original model weights and the new weights is ΔW, representing the change in weights. Therefore, a tuned model will have a new set of weights which can be represented as the original model weights plus the change in weights, W0 + ΔW.
Remember, all of these model weights are actually represented as large matrices of numbers. In math, every matrix has a property called rank (r), which describes the number of linearly independent columns or rows in a matrix. When matrices are low-rank, they have only a few columns or rows that are “important”, so we can actually decompose or split them into two smaller matrices with the most important parameters (think of it like factoring in algebra). This technique is called rank decomposition, which allows us to greatly reduce and simplify matrices while keeping the most important bits. In the context of fine-tuning, rank determines how many parameters get changed from the original model – the higher the rank, the stronger the fine-tune, giving you more granularity over the output.
According to the original LoRA paper, researchers have found that when a model is low-rank, the matrix representing the change in weights is also low-rank. Therefore, we can apply rank decomposition to our matrix representing the change in weights ΔW to create two smaller matrices A, B, where ΔW = BA. Now, the change in the model can be represented by two smaller low-rank matrices. This is why this method of fine-tuning is called Low-Rank Adaptation.
When we run inference, we only need the smaller matrices A, B to change the behavior of the model. The model weights in A, B constitute our LoRA adapter (along with a config file). At runtime, we add the model weights together, combining the original model (W0) and the LoRA adapter (A, B). Adding and subtracting are simple mathematical operations, meaning that we can quickly swap out different LoRA adapters by adding and subtracting A, B from W0.. By temporarily adjusting the weights of the original model, we modify the model’s behavior and output and as a result, we get fine-tuned inference with minimal added latency.
According to the original LoRA paper, “LoRA can reduce the number of trainable parameters by 10,000 times and the GPU memory requirement by 3 times”. Because of this, LoRA is one of the most popular methods of fine-tuning since it’s a lot less computationally expensive than a fully fine-tuned model, doesn’t add any material inference time, and is much smaller and portable.
How can you use LoRAs with Workers AI?
Workers AI is very well-suited to run LoRAs because of the way we run serverless inference. The models in our catalog are always pre-loaded on our GPUs, meaning that we keep them warm so that your requests never encounter a cold start. This means that the base model is always available, and we can dynamically load and swap out LoRA adapters as needed. We can actually plug in multiple LoRA adapters to one base model, so we can serve multiple different fine-tuned inference requests at once.
When you fine-tune with LoRA, your output will be two files: your custom model weights (in safetensors format) and an adapter config file (in json format). To create these weights yourself, you can train a LoRA on your own data using the Hugging Face PEFT (Parameter-Efficient Fine-Tuning) library combined with the Hugging Face AutoTrain LLM library. You can also run your training tasks on services such as Auto Train and Google Colab. Alternatively, there are many open-source LoRA adapters available on Hugging Face today that cover a variety of use cases.
Eventually, we want to support the LoRA training workloads on our platform, but we’ll need you to bring your trained LoRA adapters to Workers AI today, which is why we’re calling this feature Bring Your Own (BYO) LoRAs.
For the initial open beta release, we are allowing people to use LoRAs with our Mistral, Llama, and Gemma models. We have set aside versions of these models which accept LoRAs, which you can access by appending -lora to the end of the model name. Your adapter must have been fine-tuned from one of our supported base models listed below:
@cf/meta-llama/llama-2-7b-chat-hf-lora
@cf/mistral/mistral-7b-instruct-v0.2-lora
@cf/google/gemma-2b-it-lora
@cf/google/gemma-7b-it-lora
As we are launching this feature in open beta, we have some limitations today to take note of: quantized LoRA models are not yet supported, LoRA adapters must be smaller than 100MB and have up to a max rank of 8, and you can try up to 30 LoRAs per account during our initial open beta. To get started with LoRAs on Workers AI, read the Developer Docs.
As always, we expect people to use Workers AI and our new BYO LoRA feature with our Terms of Service in mind, including any model-specific restrictions on use contained in the models’ license terms.
How did we build multi-tenant LoRA serving?
Serving multiple LoRA models simultaneously poses a challenge in terms of GPU resource utilization. While it is possible to batch inference requests to a base model, it is much more challenging to batch requests with the added complexity of serving unique LoRA adapters. To tackle this problem, we leverage the Punica CUDA kernel design in combination with global cache optimizations in order to handle the memory intensive workload of multi-tenant LoRA serving while offering low inference latency.
The Punica CUDA kernel was introduced in the paper Punica: Multi-Tenant LoRA Serving as a method to serve multiple, significantly different LoRA models applied to the same base model. In comparison to previous inference techniques, the method offers substantial throughput and latency improvements. This optimization is achieved in part through enabling request batching even across requests serving different LoRA adapters.
The core of the Punica kernel system is a new CUDA kernel called Segmented Gather Matrix-Vector Multiplication (SGMV). SGMV allows a GPU to store only a single copy of the pre-trained model while serving different LoRA models. The Punica kernel design system consolidates the batching of requests for unique LoRA models to improve performance by parallelizing the feature-weight multiplication of different requests in a batch. Requests for the same LoRA model are then grouped to increase operational intensity. Initially, the GPU loads the base model while reserving most of its GPU memory for KV Cache. The LoRA components (A and B matrices) are then loaded on demand from remote storage (Cloudflare’s cache or R2) when required by an incoming request. This on demand loading introduces only milliseconds of latency, which means that multiple LoRA adapters can be seamlessly fetched and served with minimal impact on inference performance. Frequently requested LoRA adapters are cached for the fastest possible inference.
Once a requested LoRA has been cached locally, the speed it can be made available for inference is constrained only by PCIe bandwidth. Regardless, given that each request may require its own LoRA, it becomes critical that LoRA downloads and memory copy operations are performed asynchronously. The Punica scheduler tackles this exact challenge, batching only requests which currently have required LoRA weights available in GPU memory, and queueing requests that do not until the required weights are available and the request can efficiently join a batch.
By effectively managing KV cache and batching these requests, it is possible to handle significant multi-tenant LoRA-serving workloads. A further and important optimization is the use of continuous batching. Common batching methods require all requests to the same adapter to reach their stopping condition before being released. Continuous batching allows a request in a batch to be released early so that it does not need to wait for the longest running request.
Given that LLMs deployed to Cloudflare’s network are available globally, it is important that LoRA adapter models are as well. Very soon, we will implement remote model files that are cached at Cloudflare’s edge to further reduce inference latency.
A roadmap for fine-tuning on Workers AI
Launching support for LoRA adapters is an important step towards unlocking fine-tunes on our platform. In addition to the LLM fine-tunes available today, we look forward to supporting more models and a variety of task types, including image generation.
Our vision for Workers AI is to be the best place for developers to run their AI workloads — and this includes the process of fine-tuning itself. Eventually, we want to be able to run the fine-tuning training job as well as fully fine-tuned models directly on Workers AI. This unlocks many use cases for AI to be more relevant in organizations by empowering models to have more granularity and detail for specific tasks.
With AI Gateway, we will be able to help developers log their prompts and responses, which they can then use to fine-tune models with production data. Our vision is to have a one-click fine-tuning service, where log data from AI Gateway can be used to retrain a model (on Cloudflare) and then the fine-tuned model can be redeployed on Workers AI for inference. This will allow developers to personalize their AI models to fit their applications, allowing for granularity as low as a per-user level. The fine-tuned model can then be smaller and more optimized, helping users save time and money on AI inference – and the magic is that all of this can all happen within our very own Developer Platform.
We’re excited for you to try the open beta for BYO LoRAs! Read our Developer Docs for more details, and tell us what you think on Discord.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.