Tag Archives: Compliance

AWS completes the CCCS PBHVA assessment with 149 services and features in scope

Post Syndicated from Naranjan Goklani original https://aws.amazon.com/blogs/security/aws-completes-the-cccs-pbhva-assessment-with-149-services-and-features-in-scope/

We continue to expand the scope of our assurance programs at Amazon Web Services (AWS) and are pleased to announce the successful completion of our first ever Protected B High Value Assets (PBHVA) assessment with 149 assessed services and features. Completion of this assessment effective October 4, 2024, makes AWS the first cloud service provider (CSP) in Canada to meet this high security bar and provide assurance to our valued customers. This assessment also re-affirms our commitment to helping public and commercial customers achieve and maintain the highest-grade security standard for workloads with increased sensitivity.

What is the PBHVA assessment and why is it important?

The Protected B High Value Asset (PBHVA) overlay seeks to enhance the integrity and availability of customer organizational workloads that are considered to have an increased level of sensitivity. These are systems that the Government of Canada (GC) and its service providers use to support delivery of services at a national scale or that are determined to be significant for handling sensitive information. The overlay is a set of 117 controls from the ITSG-33 security control catalogue (baselined against NIST 800-53), which augments the security safeguards to enhance integrity and availability.

As of October 4, 2024, there are a total of 149 AWS services and features that were assessed by the Canadian Centre for Cyber Security (CCCS) under PBHVA assessment criteria. The assessment covers services and features that are available in both the Canada (Central) and Canada West (Calgary) AWS Regions.

How can you access the assessment?

The summary assessment is available through AWS Artifact. You can also learn more about the PBHVA assessment on our AWS PBHVA webpage.

AWS strives to continuously bring services into scope of its compliance programs to help you meet your architectural and regulatory needs. Please reach out to your AWS account team if you have questions or feedback about the PBHVA assessment.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below.

Naranjan Goklani

Naranjan is an Audit Lead for Canada. He has experience leading audits, attestations, certifications, and assessments across the Americas. Naranjan has more than 15 years of experience in risk management, security assurance, and performing technology audits. He previously worked in one of the Big 4 accounting firms and supported clients from the financial services, technology, retail, and utilities industries.

2024 ISO and CSA STAR certificates now available with two additional services

Post Syndicated from Atulsing Patil original https://aws.amazon.com/blogs/security/2024-iso-and-csa-star-certificates-now-available-with-two-additional-services/

Amazon Web Services (AWS) successfully completed a surveillance audit with no findings for ISO 9001:2015, 27001:2022, 27017:2015, 27018:2019, 27701:2019, 20000-1:2018, and 22301:2019, and Cloud Security Alliance (CSA) STAR Cloud Controls Matrix (CCM) v4.0. EY CertifyPoint auditors conducted the audit and reissued the certificates on November 29, 2024. The objective of the audit was to assess the level of compliance with the requirements of the applicable international standards.

During this surveillance audit, we added two additional AWS services to the scope since the last certification issued on July 22, 2024:

For a full list of AWS services that are certified under ISO and CSA STAR, see the AWS ISO and CSA STAR Certified page. Customers can also access the certifications in the AWS Management Console through AWS Artifact.

If you have feedback about this post, submit comments in the Comments section below.
 

Atul Patil

Atulsing Patil
Atulsing is a Compliance Program Manager at AWS. He has 27 years of consulting experience in information technology and information security management. Atulsing holds a Master of Science in Electronics degree and professional certifications such as CCSP, CISSP, CISM, CDPSE, ISO 27001 Lead Auditor, HITRUST CSF, Archer Certified Consultant, and AWS CCP.

Nimesh Ravas

Nimesh Ravasa
Nimesh is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Nimesh has 15 years of experience in information security and holds CISSP, CDPSE, CISA, PMP, CSX, AWS Solutions Architect – Associate, and AWS Security Specialty certifications.

Chinmaee Parulekar

Chinmaee Parulekar
Chinmaee is a Compliance Program Manager at AWS. She has 5 years of experience in information security. Chinmaee holds a Master of Science degree in Management Information Systems and professional certifications such as CISA.

Updated PCI DSS and PCI PIN compliance packages now available

Post Syndicated from Nivetha Chandran original https://aws.amazon.com/blogs/security/updated-pci-dss-and-pci-pin-compliance-packages-now-available/

Amazon Web Services (AWS) is pleased to announce enhancements to our Payment Card Industry (PCI) compliance portfolio, further empowering AWS customers to build and manage secure, compliant payment environments with greater ease and flexibility.

PCI Data Security Standard (DSS): Our latest AWS PCI DSS v4 Attestation of Compliance (AOC) is now available and includes six additional AWS services:

This expansion allows you to use these services while maintaining PCI DSS compliance, enabling innovation without compromising security. You can see the full list of services at AWS Services in Scope by Compliance Program.

PCI Personal Identification Number (PIN): We updated our PCI PIN AOC for two critical services:

  • AWS CloudHSM: Manage your encryption keys on FIPS 140-2 Level 3 certified hardware in your own virtual private cloud (VPC), with a dedicated, single-tenant hardware security module (HSM) solution.
  • AWS Payment Cryptography: Use payment HSMs that are PCI PIN Transaction Security (PTS) HSM certified and fully managed by AWS, with PCI PIN and point-to-point encryption (P2PE)–compliant key management.

These refreshed attestations offer you greater flexibility in deploying regulated workloads while significantly reducing your compliance overhead. You can access the PCI DSS and PIN AOC reports through AWS Artifact. This self-service portal provides on-demand access to AWS compliance reports, streamlining your audit processes.

To learn more about our PCI programs and other compliance and security programs, see the AWS Compliance Programs page. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Compliance Support page.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Nivetha Chandran
Nivetha Chandran

Nivetha is a Security Assurance Manager at AWS, where she leads multiple security and compliance initiatives. Nivetha has over ten years of experience in security assurance and holds a master’s degree in information management from the University of Washington.

Fall 2024 SOC 1, 2, and 3 reports now available with 183 services in scope

Post Syndicated from Paul Hong original https://aws.amazon.com/blogs/security/fall-2024-soc-1-2-and-3-reports-now-available-with-183-services-in-scope/

We continue to expand the scope of our assurance programs at Amazon Web Services (AWS) and are pleased to announce that the Fall 2024 System and Organization Controls (SOC) 1, 2, and 3 reports are now available. The reports cover 183 services over the 12-month period from October 1, 2023 to September 30, 2024, so that customers have a full year of assurance with the reports. These reports demonstrate our continuous commitment to adhere to the heightened expectations for cloud service providers.

Going forward, we will issue SOC reports covering a 12-month period each quarter as follows:

Report Period covered
Spring SOC 1, 2, and 3 April 1–March 31
Summer SOC 1 July 1–June 30
Fall SOC 1, 2, and 3 October 1–September 30
WWinter SOC 1 January 1–December 31

Customers can download the Fall 2024 SOC 1, 2, and 3 reports through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

AWS strives to continuously bring services into the scope of its compliance programs to help you meet your architectural and regulatory needs. If you have questions or feedback about SOC compliance, reach out to your AWS account team.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

 
If you have feedback about this post, submit comments in the Comments section below.
 

Paul Hong

Paul Hong
Paul is a Compliance Program Manager at AWS. He leads multiple security, compliance, and training initiatives within AWS, and has over 10 years of experience in security assurance. Paul holds CISSP, CEH, and CPA certifications. He has a master’s degree in accounting information systems and a bachelor’s degree in business administration from James Madison University, Virginia.

Tushar Jain

Tushar Jain
Tushar is a Compliance Program Manager at AWS, where he leads multiple security and privacy initiatives. Tushar holds a master of business administration degree from Indian Institute of Management in Shillong, India and a bachelor of technology in electronics and telecommunication engineering from Marathwada University, India. He has over 12 years of experience in information security and holds CCSK and CSXF certifications.

Michael Murphy

Michael Murphy
Michael is a Compliance Program Manager at AWS, where he leads multiple security and privacy initiatives. Michael has 12 years of experience in information security. He holds a master’s degree and a bachelor’s degree in computer engineering from Stevens Institute of Technology. He also holds CISSP, CRISC, CISA, and CISM certifications.

Nathan Samuel

Nathan Samuel
Nathan is a Compliance Program Manager at AWS, where he leads multiple security and privacy initiatives. Nathan has a bachelor of commerce degree from the University of the Witwatersrand, South Africa, and has over 21 years of experience in security assurance. He holds the CISA, CRISC, CGEIT, CISM, CDPSE, and Certified Internal Auditor certifications.

ryan wilks

Ryan Wilks
Ryan is a Compliance Program Manager at AWS, where he leads multiple security and privacy initiatives. Ryan has 13 years of experience in information security. He has a bachelor of arts degree from Rutgers University and holds ITIL, CISM, and CISA certifications.

AWS-LC FIPS 3.0: First cryptographic library to include ML-KEM in FIPS 140-3 validation

Post Syndicated from Jake Massimo original https://aws.amazon.com/blogs/security/aws-lc-fips-3-0-first-cryptographic-library-to-include-ml-kem-in-fips-140-3-validation/

We’re excited to announce that AWS-LC FIPS 3.0 has been added to the National Institute of Standards and Technology (NIST) Cryptographic Module Validation Program (CMVP) modules in process list. This latest validation of AWS-LC introduces support for Module Lattice-Based Key Encapsulation Mechanisms (ML-KEM), the new FIPS standardized post-quantum cryptographic algorithm. This is a significant step towards enhancing the long-term confidentiality of our most sensitive customer workflows, including U.S. federal government communications.

This validation makes AWS LibCrypto (AWS-LC) the first open source cryptographic module to provide post-quantum algorithm support within the FIPS module. Organizations that require FIPS-validated cryptographic modules—such as those operating under FedRAMP, FISMA, HIPAA, and other federal compliance frameworks—can now use these algorithms within AWS-LC.

This announcement is part of the long-term promise made by AWS-LC of continuous validation to obtain new FIPS 140-3 certificates. AWS-LC obtained its first certificate in October 2023 for AWS-LC-FIPS 1.0. A subsequent version of the library, AWS-LC-FIPS 2.0, was certified in October 2024. In this post, we discuss our FIPS-validation of post-quantum cryptographic algorithm ML-KEM, the performance improvements of existing algorithms in AWS-LC FIPS 2.0 and 3.0, and the new algorithm support added for version 3.0. We also discuss how you can use the new algorithms to implement hybrid post-quantum cipher suites, along with configuration options that you can set up today to help protect against future threats.

FIPS post-quantum cryptography

Large-scale quantum computers pose a threat to the long-term confidentiality of the data that we protect under public-key cryptography today. In what’s known as a record-now, decrypt-later attack, an adversary records internet traffic today, capturing key exchanges and encrypted communication. Then, when a sufficiently powerful quantum computer is available, the adversary can retroactively recover shared secrets and encryption keys by solving the underlying hardness problem.

ML-KEM is one of the new key encapsulation mechanisms that’s being standardized by NIST in an effort to protect the uses of public key cryptography from quantum threats. Much like RSA, Diffie-Hellman (DH), or Elliptic-curve Diffie-Hellman (ECDH) key exchange, it works by establishing a shared secret between two parties. However, unlike RSA or DH, ML-KEM bases the key exchange on an underlying problem that is believed to be hard for quantum computers to solve.

Today, we don’t know how to build such a large-scale quantum computer. Significant scientific research is needed before such a computer can be built. However, you can mitigate the risk of record-now, decrypt-later attacks by introducing post-quantum algorithms such as ML-KEM into your key exchange protocols today. We recommend adopting a hybrid key exchange approach that combines a traditional key exchange method—such as ECDH—with ML-KEM to hedge against current and future adversaries. Later in this post, we show you how you can implement hybrid post-quantum cipher suites today to protect against future threats.

AWS-LC FIPS 3.0 includes the ML-KEM algorithm for all three provided parameter sets, ML-KEM-512, ML-KEM-768, and ML-KEM-1024. The three parameter sets provide differing levels of security strength as specified by NIST (see FIPS 203 [9, Sect. 5.6] or the post-quantum security evaluation criteria). ML-KEM-768 is recommended for general-purpose use cases, ML-KEM-1024 is designed for applications that require a higher security level or adherence to explicit directives such as the Commercial National Security Algorithm Suite (CNSA) 2.0 for National Security System owners and operators.

Algorithm NIST security category Public key (B) Private key (B) Ciphertext (B)
ML-KEM-512 1 800 1632 768
ML-KEM-768 3 1184 2400 1088
ML-KEM-1024 5 1568 3168 1568

Table 1. Security strength category, public key, private key, and ciphertext sizes in bytes for the three parameter sets of ML-KEM

Integration with s2n-tls

ML-KEM is now available in our open source TLS implementation, s2n-tls, through hybrid key exchange for TLS 1.3 (draft-ietf-tls-hybrid-design). We’ve also added support for hybrid ECDHE-ML-KEM key agreement for TLS 1.3 (draft-kwiatkowski-tls-ecdhe-mlkem), along with new key share identifiers for Curve x25519 and ML-KEM-768.

For hybrid key establishment in FIPS 140-approved mode, one component algorithm must be a NIST-approved mechanism (detailed in NIST post-quantum FAQs). With ML-KEM added to the list of NIST-approved algorithms, you can now include non-FIPS standardized algorithms like Curve x25519 in hybrid cipher suites. By configuring your TLS cipher suite to use ML-KEM-768 and x25519 (draft-kwiatkowski-tls-ecdhe-mlkem), you can use x25519 within a FIPS-validated cryptographic module for the first time. This can facilitate more efficient key exchange through the highly optimized and functionally verified Curve x25519 implementation provided by AWS-LC.

New algorithms and new implementations

Two integral parts of our commitment to continuous validation of AWS-LC FIPS are to include new algorithms as approved cryptographic services and new implementations of existing algorithms that provide performance improvements and functional correctness.

New algorithms

We’re committed to continually validating new algorithms so that builders can adopt FIPS-validated cryptography by including the latest revisions of approved cryptographic algorithms and supporting new primitives. Validating new algorithms in their latest standardized revision helps ensure that our cryptographic tool-kit is providing high-assurance implementations that achieve compliance with globally recognized standards.

In AWS-LC FIPS 3.0 we’ve added the latest member of the Secure Hash Algorithm standard SHA-3 to the module. The SHA-3 family is a cryptographic primitive used to support a variety of algorithms. In AWS-LC FIPS 3.0, we’ve integrated ECDSA and RSA signature generation and verification with SHA-3 and within the post-quantum algorithm ML-KEM. In AWS-LC, ML-KEM calls into our FIPS-validated SHA-3 functions, which provide optimized implementations of SHA-3 and SHAKE hashing procedures. This means that as we continually refine and optimize our AWS-LC SHA-3 implementation, we’ll continue to see performance increases across algorithms that use the primitive, such as ML-KEM.

EdDSA is a digital signature algorithm based on elliptic curves using the curve Ed25519. It was added to NIST’s updated Digital Signature Standard (DSS), FIPS 186-5. This signature algorithm is now offered as part of the AWS-LC 3.0 FIPS module. For key agreement, the Single-step Key Derivation Function (SSKDF) used to derive keys from a shared secret (SP 800-56Cr2) is available both in the digest-based and HMAC-based specifications. It can be used, for example, to derive a key from a shared secret produced by KMS when using ECDH. Further keys can be derived from that original key using a Key-based Key Derivation Function (KBKDF)—SP 800-108r1—which is available using a counter-mode based on HMAC.

Performance improvements

We focused on increasing the performance of public-key cryptography algorithms widely used in transport protocols such as the TLS protocol. For example, RSA signatures on Graviton2 are 81 percent faster for bit-length 2048, 33 percent for 3072, and 94 percent for 4096, with added formal verification of functional correctness of the main operation. Using Intel’s AVX512 Integer Fused Multiply Add (IFMA) instructions—available starting from 3rd Gen Intel Xeon—Intel developers contributed an RSA implementation that employs these instruction and the wide AVX512 registers, which are twice as fast as the existing implementation.

We increased throughput for EdDSA signing by an average of 108 percent and for verifying by 37 percent. This average is taken over three environments: Graviton2, Graviton3, and Intel Ice Lake (Intel Xeon Platinum 8375C CPU). This boost in performance is achieved by integrating assembly implementations of the core operation for each target from the s2n-bignum library. That, in addition to the careful constant-time implementation of the core operations, is how each one has been proven to be functionally correct.

In Figure 1 that follows, we highlight the percentage of performance improvements compared to AWS-LC FIPS 1.0 in versions 2.0 and 3.0. The improvements achieved in 2.0 are maintained in 3.0 and are not repeated in the graph. The graph also includes symmetric-key improvements. In AES-256-GCM, which is widely used in TLS to encrypt the communication after the session has been established, the increase is on average 115 percent across Intel Ice Lake and Graviton4 to encrypt a 16 KB message. In AES-256-XTS, which is used in disk storage, encrypting a 256 B input is 360 percent faster on Intel Ice Lake and 90 percent faster on Graviton4.

Figure 1: Graph of performance improvements in versions 2.0 and 3.0 of AWS-LC FIPS

Figure 1: Graph of performance improvements in versions 2.0 and 3.0 of AWS-LC FIPS

How to use ML-KEM today

You can configure both s2n-tls and AWS-LC TLS libraries to enable hybrid post-quantum security with ML-KEM today by enabling X25519MLKEM768 and SecP256r1MLKEM768 for key exchange. We’ve integrated support for both of these hybrid algorithms in AWS-LC libssl and s2n-tls using each library’s exisiting TLS configuration APIs. To negotiate a TLS connection, use one of the following commands:

# AWS-LC Client CLI Example
./aws-lc/build/tool/bssl s_client -curves X25519MLKEM768:SecP256r1MLKEM768:X25519 -connect <hostname>:<port>
# S2N-tls Client CLI Example
./s2n/build/bin/s2nc -c default_pq -i <hostname> <port>

Conclusion

In this post, we described the ongoing development, optimization, and validation of the cryptography that we provide to our customers and products through our open source cryptographic library, AWS-LC. We introduced the addition of FIPS-validated post-quantum algorithms and provided configuration options to begin using these algorithms today to protect against future threats.

AWS-LC-FIPS 3.0 is part of our commitment to continually validate new versions of AWS-LC as we add new algorithms within the FIPS boundary as they become specified, and as we raise the performance and formal verification bar on existing algorithms. Through this commitment, we continue to support the wider developer community of Rust, Java and Python developers by providing integrations into the AWS Libcrypto for Rust (aws-lc-rs) and ACCP 2.0 libraries. We facilitate integration into CPython so that you can build against AWS-LC and use it for all cryptography in the Python standard library. We enabled rustls to provide FIPS support.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Jake Massimo
Jake Massimo

Jake is an Applied Scientist on the AWS Cryptography team. His work interfaces Amazon with the global cryptographic community through participation in international conferences, academic literature, and standards organizations with a goal of influencing the adoption of post-quantum cloud-scale cryptographic technology. Recently, his focus has been developing the AWS cryptography library to support post-quantum migration.
Nevine Ebeid
Nevine Ebeid

Nevine is a Senior Applied Scientist at AWS Cryptography where she focuses on algorithms development, machine-level optimizations and FIPS 140-3 requirements for AWS-LC, the cryptographic library of AWS. Prior to joining AWS, Nevine worked in the research and development of various cryptographic libraries and protocols in automotive and mobile security applications.

AWS Network Firewall Geographic IP Filtering launch

Post Syndicated from Prasanjit Tiwari original https://aws.amazon.com/blogs/security/aws-network-firewall-geographic-ip-filtering-launch/

AWS Network Firewall is a managed service that provides a convenient way to deploy essential network protections for your virtual private clouds (VPCs). In this blog post, we discuss Geographic IP Filtering, a new feature of Network Firewall that you can use to filter traffic based on geographic location and meet compliance requirements.

Customers with internet-facing applications are constantly in need of advanced security features to protect their applications from threat actors. This includes restricting traffic to and from their workloads in Amazon Web Services (AWS) to certain geographies because of security risk. Customers operating in highly regulated industries—such as banking, public sector, or insurance—might have specific security requirements that can be addressed by Geographic IP Filtering.

Previously, customers had to rely on third-party tools for retrieving an IP address list of specific countries and updating their firewall rules on a regular basis to meet applicable requirements. Now, with Geographic IP Filtering on Network Firewall, you can protect your application workloads based on the geolocation of the IP address. As new IP addresses are assigned by the Internet Assigned Numbers Authority (IANA), the Geographic IP database underneath Network Firewall is automatically updated so that the service can consistently filter inbound and outbound traffic from specific countries based on country codes. It supports IPv4 and IPv6 traffic.

Geographic IP Filtering is supported in all AWS Regions where Network Firewall is available today, including the AWS GovCloud (US) Regions.

Set up Geographic IP Filtering in Network Firewall

You can use Network Firewall to inspect network traffic and protect your VPCs using layer 3–7 rules (network layer to application layer of the OSI model). When traffic reaches Network Firewall, it will identify the location of the source and destination IP address from the Geographic IP database and block traffic if you have a firewall rule to block that location. You can choose to pass, drop, reject, or create an alert for traffic coming from or going to specific countries.

Before setting up Geographic IP Filtering rules, you need to deploy Network Firewall and attach a firewall policy. You can learn more about these steps in the Network Firewall Getting Started guide. You can configure Network Firewall Geographic IP Filtering in minutes using the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS SDK, or the Network Firewall API.

To configure Geographic IP Filtering rules using the console:

  1. Sign in to the AWS Management Console and open the Amazon VPC console.
  2. In the navigation pane, under Network Firewall, choose Network Firewall rule groups.
  3. Choose Create rule group.
  4. In the Create rule group page, for the Rule group type, select Stateful rule group.
  5. For the Rule group format, select Standard stateful rule.
  6. For Rule evaluation order, select either Strict order (recommended) or Action order.
  7. Enter a name for the stateful rule group.
  8. For Capacity, enter the maximum capacity you want to allow for the stateful rule group.
  9. Under Standard stateful rules, for Geographic IP Filtering, select whether you want to Disable Geographic IP filtering, Match only selected countries, or Match all but selected countries.
  10. If you opt for Geographic IP Filtering, then select the Geographic IP traffic direction and Country codes that you want to filter the traffic for.
  11. Enter the appropriate values for Protocol, Source, Source port, Destination, and Destination port.
  12. For Action, select the action that you want Network Firewall to take when a packet matches the rule settings.

    Figure 1: Standard stateful rule

    Figure 1: Standard stateful rule

  13. Click Add rule and then review the rule to create the rule group.

    Figure 2: Geographic IP Filtering rules

    Figure 2: Geographic IP Filtering rules

Suricata compatibility

You can also use Geographic IP filtering with Suricata-compatible rule strings using the geoip keyword.

To create a Suricata compatible rule string:

  1. Follow steps 1 through 4 of the previous procedure.
  2. For the Rule group format, select Suricata compatible rule string.
  3. For Rule evaluation order, select either Strict order (recommended) or Action order.
  4. Enter a name for the stateful rule group.
  5. For Capacity, enter the maximum capacity you want to allow for the stateful rule group.
  6. Under Suricata compatible rule string, enter an appropriate string based on your source and destination along with the country code to filter traffic for. To use a Geographic IP filter, provide the geoip keyword, the filter type, and the country codes for the countries that you want to filter for.
  7. Suricata supports filtering for source and destination IPs. You can filter on either of these types by itself, by specifying dst or src. You can filter on the two types together with AND or OR logic, by specifying both or any.

For example, the following sample Suricata rule string drops traffic originating from Japan:

drop ip any any -> any any (msg:"Geographic IP from JP,Japan"; geoip:src,JP; sid:55555555; rev:1;)

Note that Suricata determines the location of requests using MaxMind GeoIP databases. MaxMind reports very high accuracy of their data at the country level, although accuracy varies according to factors such as country and type of IP. For more information about MaxMind, see MaxMind IP Geolocation.

If you think any of the Geographic IP data is incorrect, you can submit a correction request to MaxMind at MaxMind Correct GeoIP Data.

Logging Geographic IP Filtering

You can configure Network Firewall logging for your firewall’s stateful engine to get detailed information about the packet and any stateful rule action taken against the packet. There are no changes to the logging and monitoring mechanism with the introduction of the Geographic IP Filtering feature. However, by explicitly specifying the msg and metadata keywords, you can see additional geographic information in the alert logs that can help with troubleshooting. If these keywords aren’t specified in the Suricata rule string, the log event will not show any geographic information.

Suricata rule examples

In this section, you will find examples of Suricata rule strings to pass, block, reject, and alert on traffic to or from a specific country.

Example 1: To pass ingress traffic from a specific country

The following example passes ingress traffic from India.

Note: The rule evaluation order should be set to Strict for alert logs to be generated in this example. If the rule evaluation order is set to Action, then although the traffic will pass, alert logs will not be generated.

alert ip $EXTERNAL_NET any -> $HOME_NET any (msg:"Ingress traffic from IN allowed"; flow:to_server; geoip:src,IN; metadata:geo IN; sid:202409301;)
pass ip $EXTERNAL_NET any -> $HOME_NET any (msg:"Ingress traffic from IN allowed"; flow:to_server; geoip:src,IN; metadata:geo IN; sid:202409302;)

The following are the alert and flow logs for Example 1.

Alert logs:

{
    "firewall_name": "Test-NFW",
    "availability_zone": "eu-north-1a",
    "event_timestamp": "1731102856",
    "event": {
        "src_ip": "13.127.20.X",
        "src_port": 56630,
        "event_type": "alert",
        "alert": {
            "severity": 3,
            "signature_id": 202409301,
            "rev": 0,
            "metadata": {
                "geo": ["IN"]
            },
            "signature": "Ingress traffic from IN allowed",
            "action": "allowed",
            "category": ""
        },
        "flow_id": 234143298308779,
        "dest_ip": "172.31.2.4",
        "proto": "TCP",
        "verdict": {
            "action": "pass"
        },
        "dest_port": 80,
        "pkt_src": "geneve encapsulation",
        "timestamp": "2024-11-08T21:54:16.972019+0000",
        "direction": "to_server"
    }
}

Flow logs from source to destination:

{
    "firewall_name": "Test-NFW",
    "availability_zone": "eu-north-1a",
    "event_timestamp": "1731102918",
    "event": {
        "tcp": {
            "tcp_flags": "13",
            "syn": true,
            "fin": true,
            "ack": true
        },
        "app_proto": "unknown",
        "src_ip": "13.127.20.X",
        "src_port": 56630,
        "netflow": {
            "pkts": 4,
            "bytes": 216,
            "start": "2024-11-08T21:54:16.972019+0000",
            "end": "2024-11-08T21:54:17.263030+0000",
            "age": 1,
            "min_ttl": 112,
            "max_ttl": 112
        },
        "event_type": "netflow",
        "flow_id": 234143298308779,
        "dest_ip": "172.31.2.4",
        "proto": "TCP",
        "dest_port": 80,
        "timestamp": "2024-11-08T21:55:18.257416+0000"
    }
}

Flow logs from destination to source:

{
    "firewall_name": "Test-NFW",
    "availability_zone": "eu-north-1a",
    "event_timestamp": "1731102918",
    "event": {
        "tcp": {
            "tcp_flags": "13",
            "syn": true,
            "fin": true,
            "ack": true
        },
        "app_proto": "unknown",
        "src_ip": "172.31.2.4",
        "src_port": 80,
        "netflow": {
            "pkts": 2,
            "bytes": 112,
            "start": "2024-11-08T21:54:16.972019+0000",
            "end": "2024-11-08T21:54:17.263030+0000",
            "age": 1,
            "min_ttl": 126,
            "max_ttl": 126
        },
        "event_type": "netflow",
        "flow_id": 234143298308779,
        "dest_ip": "13.127.20.X",
        "proto": "TCP",
        "dest_port": 56630,
        "timestamp": "2024-11-08T21:55:18.257449+0000"
    }
}

Example 2: To block ingress traffic from a specific country

The following example blocks ingress traffic from Japan.

drop ip $EXTERNAL_NET any -> $HOME_NET any (msg:"Ingress traffic from JP blocked"; flow:to_server; geoip:any,JP; metadata:geo JP; sid:202409303;)

Example 3: To block ingress SSH traffic from a specific country

The following example blocks ingress SSH traffic from Russia.

drop ssh $EXTERNAL_NET any -> $HOME_NET any (msg:"Ingress SSH traffic from RU blocked"; flow:to_server; geoip:src,RU; metadata:geo RU; sid:202409304;)

Example 4: To reject egress TCP traffic to a specific country:

The following example rejects egress TCP traffic to Iran.

reject tcp $HOME_NET any -> $EXTERNAL_NET any (msg:"Egress traffic to IR rejected"; flow:to_server; geoip:dst,IR; metadata:geo IR; sid:202409305;)

Example 5: To alert on traffic originating from or destined to specific country

The following example alerts on traffic that originates from Venezuela.

alert ip any any -> any any (msg:"Geographic IP is from VE, Venezuela"; geoip:any,VE; sid: 202409306;)

Conclusion

You can use the new Geographic IP Filtering feature in AWS Network Firewall to enhance your security posture by controlling traffic based on geographic locations. In this post, you learned about the key concepts, configuration steps, and examples for implementing the Geographic IP Filtering feature in Network Firewall. By using this feature, businesses can protect their networks from potentially harmful traffic and control which geographic locations can interact with their infrastructure. As cyber threats continue to evolve, the Geographic IP Filtering feature serves as a vital tool for strengthening network security.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Prasanjit Tiwari
Prasanjit Tiwari

Prasanjit is a Cloud Support Engineer II based out of Virginia, USA. He has a Master of Science in Telecommunications Engineering from the University of Maryland. He is a WAF and Route 53 subject matter expert and enjoys working on networking and perimeter security services. He is enthusiastic about using innovative solutions to address customer challenges.
Dhiren Patel
Dhiren Patel

Dhiren is a Cloud Support Engineer-II based out of Virginia, USA. He has a Master of Science in Electrical and Computer Engineering from New York University. As a WAF and Route 53 subject matter expert, he specializes in AWS networking and security services. He’s passionate about helping customers solve their AWS issues and get the best cloud experience possible through AWS.

Exploring the benefits of artificial intelligence while maintaining digital sovereignty

Post Syndicated from Max Peterson original https://aws.amazon.com/blogs/security/exploring-benefits-of-artificial-intelligence-while-maintaining-digital-sovereignty/

Around the world, organizations are evaluating and embracing artificial intelligence (AI) and machine learning (ML) to drive innovation and efficiency. From accelerating research and enhancing customer experiences to optimizing business processes, improving patient outcomes, and enriching public services, the transformative potential of AI is being realized across sectors. Although using emerging technologies helps drive positive outcomes, leaders worldwide must balance these benefits with the need to maintain security, compliance, and resilience. Many organizations, including those in the public sector and regulated industries, are investing in generative AI applications powered by large language models (LLMs) and other foundation models (FMs) because these applications can transform and scale their work and provide better experiences for customers. Beyond computing power, unlocking this AI potential resides in the AI applications that organizations can create based on a variety of AI/ML development services, models, and data sources. Organizations must navigate the complexity of building AI applications in light of existing and emerging regulatory regimes while verifying that their AI applications and related data are secure, protected, and resilient to risks and threats.

AWS offers a wide range of AI/ML services and capabilities, built on our sovereign-by-design foundation, that are making it simpler for our customers to meet their digital sovereignty needs while getting the security, control, compliance, and resilience that they need. For example, Amazon Bedrock is a fully managed service that offers a choice of high-performing FMs from leading AI companies such as AI21 Labs, Anthropic, Cohere, Meta, Mistral AI, and Stability AI through a single API, along with a broad set of capabilities to build generative AI applications with security, privacy, and responsible AI. Amazon SageMaker provides tools and infrastructure to build, train, and deploy ML models at scale while supporting responsible AI with governance controls and access to pretrained models.

Innovating securely across the AI lifecycle

Security is and always has been our top priority at AWS. AWS customers benefit from our ongoing investment in data centers, networks, custom hardware, and secure software services, built to satisfy the requirements of the most security-sensitive organizations, including the government, healthcare, and financial services. We have always believed that it is essential that customers have control over their data and its location. That’s why we architected the AWS Cloud to be secure and sovereign-by-design from day one. We remain committed to giving our customers more control and choice so that they can use the full power of AWS while meeting their unique digital sovereignty needs.

As organizations develop and implement generative AI, they want to make sure that their data and applications are secured across the AI lifecycle, including data preparation, training, and inferencing. To help ensure the confidentiality and integrity of customer data, all of our Nitro-based Amazon Elastic Compute Cloud (Amazon EC2) instances that run ML accelerators such as AWS Inferentia and AWS Trainium, and graphics processing units (GPUs) such as P4, P5, G5, and G6, are backed by the industry-leading security capabilities of the AWS Nitro System. By design, there is no mechanism for anyone at AWS to access Nitro EC2 instances that customers use to run their workloads. The NCC Group, an independent cybersecurity firm, has validated the design of the Nitro System.

We take a secure approach to generative AI and make it practical for our customers to secure their generative AI workloads across the generative AI stack so that they can focus on building and scaling. All AWS services—including generative AI services—support encryption, and we continue to innovate and invest in controls and encryption features that allow our customers to encrypt everything everywhere.

For example, Amazon Bedrock uses encryption to protect data in transit and at rest, and data remains in the AWS Region where Amazon Bedrock is being used. Customer data, such as prompts, completions, custom models, and data used for fine-tuning or continued pre-training, is not used for Amazon Bedrock service improvement and is never shared with third-party model providers. When customers fine-tune a model in Amazon Bedrock, the data is never exposed to the public internet, never leaves the AWS network, is securely transferred through a customer’s virtual private cloud (VPN), and is encrypted in transit and at rest.

SageMaker protects ML model artifacts and other system artifacts by encrypting data in transit and at rest. Amazon Bedrock and SageMaker integrate with AWS Key Management Service (AWS KMS) so that customers can securely manage cryptographic keys. AWS KMS is designed so that no one—not even AWS employees—can retrieve plaintext keys from the service.

Developing responsibly

The responsible development and use of AI is a priority for AWS. We believe that AI should take a people-centric approach that makes AI safe, fair, secure, and robust. We are committed to supporting customers with responsible AI and helping them build fairer and more transparent AI applications to foster trust, meet regulatory requirements, and use AI to benefit their business and stakeholders. AWS is the first major cloud service provider to announce ISO/IEC 42001 accredited certification for AI services, covering Amazon Bedrock, Amazon Q Business, Amazon Textract, and Amazon Transcribe. ISO/IEC 42001 is an international management system standard that outlines requirements and controls for organizations to promote the responsible development and use of AI systems.

We take responsible AI from theory into practice by providing the necessary tools, guidance, and resources, including Amazon Bedrock Guardrails to help implement safeguards tailored to customer generative AI applications and aligned with their responsible AI policies, or Model Evaluation on Amazon Bedrock to evaluate, compare, and select the best FMs for specific use cases based on custom metrics, such as accuracy, robustness, and toxicity. Additionally, Amazon SageMaker Model Monitor automatically detects and alerts customers of inaccurate predictions from deployed models. We continue to publish AI Service Cards to enhance transparency by providing a single place to find information on the intended use cases and limitations, responsible AI design choices, and performance optimization best practices for our AI services and models.

Building resilience

Resilience plays a pivotal role in the development of any workload, and AI/ML workloads are no different. Customers need to know that their workloads in the cloud will continue to operate in the face of natural disasters, network disruptions, or disruptions due to geopolitical crises. AWS delivers the highest network availability of any cloud provider and is the only cloud provider to offer three or more Availability Zones (AZs) in all Regions, providing more redundancy. Understanding and prioritizing resilience is crucial for generative AI workloads to meet organizational availability and business continuity requirements. We have published guidance on designing generative AI workloads for resilience. To enable higher throughput and enhanced resilience during periods of peak demands in Amazon Bedrock, customers can use cross-region inference to distribute traffic across multiple Regions. For customers with specific European Union data sovereignty requirements, we are launching the AWS European Sovereign Cloud in 2025 to offer an additional layer of control and resilience.

Supporting choice and flexibility

It’s important that customers have access to diverse AI technologies, while having the freedom to choose the right solutions to meet their needs. AWS provides more diversity, choice, and flexibility so that customers can select the AI solution that best aligns with their specific requirements, whether that’s using open-source models, proprietary solutions, or their own custom AI models. For example, we understand the importance of open-source AI in fostering transparency, collaboration, and rapid innovation. Open-source models enable scrutiny of vulnerabilities, drive security improvements, and support research on AI safety. Amazon SageMaker JumpStart provides pretrained, open-source models for a wide range of common use cases. To provide practitioners and developers with the guidance and tools that they need to create secure-by-design AI systems, we are a founding member of the open-source initiative Coalition for Secure AI (CoSAI).

Also, our commitment to portability and interoperability helps ensure that customers can move easily between environments. For customers changing IT providers, we’ve taken concrete steps to lower costs, and AWS is actively engaged in efforts to facilitate switching between cloud providers, including through our support of the Cloud Infrastructure Service Providers in Europe (CISPE) Cloud Switching Framework, which lays out guidance to assist providers and customers in the switching process. This gives organizations the flexibility to adapt their cloud and AI strategies as their needs evolve.

We remain committed to providing customers with a choice of diverse AI technologies, along with secure and compliant ways to build their AI applications throughout the development lifecycle. Through this approach, customers can enhance the security, compliance, and resilience of their systems.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Max Peterson
Max Peterson

Max is the Vice President of AWS Sovereign Cloud. He leads efforts to ensure that AWS customers around the world have the most advanced set of sovereignty controls, privacy safeguards, and security features available in the cloud. Previously, Max served as the VP of AWS Worldwide Public Sector (WWPS) and created and led the WWPS International Sales division, with a focus on empowering government, education, healthcare, aerospace and satellite, and nonprofit organizations to drive rapid innovation while meeting evolving compliance, security, and policy requirements. Max has over 30 years of public sector experience and served in other technology leadership roles before joining Amazon. Max has earned both a Bachelor of Arts in Finance and Master of Business Administration in Management Information Systems from the University of Maryland.

Comparing DORA, SOX and PCI DSS: What Businesses Need to Know

Post Syndicated from Editor original https://nebosystems.eu/comparing-sox-dora-pci-dss/

In today’s interconnected business environment, organizations must navigate an increasingly complex regulatory landscape. Key regulatory requirements such as, the Digital Operational Resilience Act (DORA), the Sarbanes-Oxley Act (SOX) and the Payment Card Industry Data Security Standard (PCI DSS) are essential in ensuring financial transparency, operational resilience and data security. But what sets them apart and where do they overlap? Let’s explore.

What Are SOX, DORA, and PCI DSS?

  • SOX: Introduced in 2002, the Sarbanes-Oxley Act ensures accurate financial reporting and corporate accountability. It applies primarily to U.S.-based public companies, emphasizing internal controls and financial disclosures.
  • DORA: Enacted by the EU, the Digital Operational Resilience Act focuses on digital operational resilience for financial institutions. It establishes robust guidelines for managing ICT (Information and Communication Technology) risks, ensuring businesses can withstand cyber incidents.
  • PCI DSS: A global standard created to secure payment card data, the Payment Card Industry Data Security Standard applies to any organization handling cardholder information. It mandates rigorous security measures to prevent data breaches.

Key Differences

  SOX DORA PCI DSS
Scope U.S. public companies. (Section 302, 404) EU financial entities. (Article 2) Global organizations handling card data. (Requirement 1)
Primary Concern Financial reporting accuracy. (Section 404) Operational resilience and cybersecurity. (Article 5, Article 6) Payment data security. (Requirement 3, 4)
Enforcement SEC and PCAOB. EU financial regulators. (Article 46) Payment brands (Visa, Mastercard).
Specificity in IT Limited to financial systems. (Section 404) Comprehensive ICT and operational risks. (Article 11, Article 15) Highly prescriptive for payment environments. (Requirement 12)

Overlapping Areas Across SOX, DORA, and PCI DSS

While SOX, DORA, and PCI DSS have distinct scopes, they share common objectives in risk management, incident response and compliance auditing:

  SOX DORA PCI DSS
Risk Management Focuses on risks to financial reporting systems. Emphasizes managing ICT and operational risks. (Article 5, DORA Regulation) Requires mitigating risks to payment data. (Requirement 12)
Incident Response Requires procedures to disclose financial data breaches. (Section 302) Mandates reporting and responding to ICT disruptions. (Article 15) Specifies response plans for payment data breaches. (Requirement 12)
Third-Party Oversight Requires oversight of third parties impacting financial reporting. (Section 404) Regulates third-party ICT providers for financial entities. (Article 28) Ensures third-party service providers comply with security standards. (Requirement 12)
Auditing and Compliance Requires annual audits of internal controls. (Section 404) Implements operational resilience assessments and testing. (Article 7) Demands regular audits and vulnerability scans for payment systems. (PCI DSS v4.0)
Data Integrity Ensures accuracy of financial records. Focuses on maintaining operational and ICT system integrity. (Article 6) Protects cardholder data integrity and confidentiality. (PCI DSS v4.0)

Common Technical Measures to Consider

Although SOX, DORA, and PCI DSS have distinct objectives, they share several technical measures that businesses can implement to align their compliance efforts. These measures not only enhance security but also streamline adherence to multiple frameworks.

Technical Measure SOX DORA PCI DSS
Access Controls User restrictions and authentication. Role-based access and secure authentication (Article 6). Strict access control requirements (Req. 7, 8).
Data Encryption Encryption for sensitive data. Encryption for ICT-related data (Article 6). Encryption of cardholder data (Req. 3, 4).
Monitoring and Logging Log unauthorized access or changes. Logging for ICT incident monitoring (Article 15). System and data access logging (Req. 10).
Testing and Assessments Regular testing of IT controls. Penetration and resilience testing (Article 23). Penetration testing and scans (Req. 11).
Backup and Recovery Backup systems for financial data. Backup and disaster recovery plans (Article 11). Backup solutions for cardholder data (Req. 12).
Network Security Secure networks for data protection. Network defenses (firewalls, IDS) (Article 6). Firewalls, secure configurations (Req. 1, 2).
Multi-Factor Authentication Often recommended. Mandatory for critical ICT systems (Article 6). Required for sensitive systems (Req. 8).

Why This Matters to Your Business

For companies operating in regulated industries or handling sensitive data, understanding these frameworks is critical. Compliance not only protects against fines and reputational damage but also fosters trust among customers and stakeholders.

For example:

  • If your company is a public entity in the U.S., SOX compliance ensures the accuracy of your financial statements.
  • If you’re a financial institution in the EU, DORA equips you to handle cyber risks and operational challenges.
  • Handling payment card transactions, PCI DSS safeguards your customers’ data and strengthens your security posture.

The Cost of Non-Compliance

Failing to comply with SOX, DORA, or PCI DSS doesn’t just result in regulatory scrutiny—it can lead to significant financial penalties, legal liabilities and reputational damage. Here’s a breakdown:

SOX (Sarbanes-Oxley Act)

  • Corporate officers who willfully certify false financial statements can face fines up to $5 million and/or imprisonment for up to 20 years​ (Section 906).
  • Tampering with records or obstructing investigations can lead to criminal penalties, including imprisonment for up to 20 years​ (Section 802).

DORA (Digital Operational Resilience Act)

  • Financial entities in violation of DORA can be fined up to 2% of annual global turnover for severe breaches of operational resilience requirements, such as inadequate ICT risk management or failing to report major incidents​.
  • Specific penalties vary by Member State within the EU but are harmonized to ensure consistency and proportionality​.

PCI DSS

Non-compliance penalties are typically imposed by payment brands like Visa and Mastercard. These include:

  • Fines ranging from $5,000 to $100,000 per month until compliance is achieved.
  • Potential revocation of card processing privileges and higher transaction fees​.

How to Align with Multiple Regulatory Requirements

Organizations such as a multinational bank operating in the EU or a retailer processing credit card transactions globally, must comply with multiple regulatory requirements. Here’s how to streamline compliance:

  • Integrated Risk Management: Build policies that address financial, ICT and data security risks holistically.
  • Unified Incident Response Plans: Standardize response procedures for data breaches, cyber disruptions, and financial irregularities. This unified approach minimizes confusion and ensures timely action during incidents.
  • Auditing for All: Conduct comprehensive audits that meet SOX, DORA, and PCI DSS requirements.

Through these measures, organizations can reduce complexity, improve resource utilization, and ensure they remain compliant across all frameworks.

Practical Benefits for Your Business

Adopting a unified approach to compliance doesn’t just meet regulatory obligations—it also delivers practical advantages:

  • Cost Savings: Streamlining risk management and auditing across frameworks reduces duplicated efforts and optimizes resource allocation.
  • Enhanced Security: Implementing shared technical measures like encryption, logging, and access controls improves protection for all critical systems and data.
  • Business Continuity: Resilience testing and incident response plans ensure your organization can recover quickly from disruptions, safeguarding operations and customer trust.

By proactively addressing these frameworks, businesses can turn compliance into a strategic advantage, fostering growth and stability in a competitive marketplace.

In Conclusion

Regulatory requirements like SOX, DORA and PCI DSS provide a robust foundation for financial integrity, operational resilience and data security. By understanding their differences and leveraging their overlaps, businesses can create a compliance strategy that not only meets legal obligations but also drives confidence in their operations.

Need help navigating these regulatory requirements? Contact us for tailored solutions to align your business with today’s compliance standards.


References:

Digital Operational Resilience Act (EU) 2022/2554. EUR-Lex.

Payment Card Industry Data Security Standard. Requirements and Testing Procedures, Version 4.0.1, June 2024.

Sarbanes-Oxley Act. Public Law 107–204, Approved July 30, 2002.

Introducing Access for Infrastructure: SSH

Post Syndicated from Sharon Goldberg original https://blog.cloudflare.com/intro-access-for-infrastructure-ssh

BastionZero joined Cloudflare in May 2024. We are thrilled to announce Access for Infrastructure as BastionZero’s native integration into our SASE platform, Cloudflare One. Access for Infrastructure will enable organizations to apply Zero Trust controls in front of their servers, databases, network devices, Kubernetes clusters, and more. Today, we’re announcing short-lived SSH access as the first available feature. Over the coming months we will announce support for other popular infrastructure access target types like Remote Desktop Protocol (RDP), Kubernetes, and databases.

Applying Zero Trust principles to infrastructure

Organizations have embraced Zero Trust initiatives that modernize secure access to web applications and networks, but often the strategies they use to manage privileged access to their infrastructure can be siloed, overcomplicated, or ineffective. When we speak to customers about their infrastructure access solution, we see common themes and pain points:

  • Too risky: Long-lived credentials and shared keys get passed around and inflate the risk of compromise, excessive permissions, and lateral movement

  • Too clunky: Manual credential rotations and poor visibility into infrastructure access slow down incident response and compliance efforts

Some organizations have dealt with the problem of privileged access to their infrastructure by purchasing a Privileged Access Management (PAM) solution or by building a homegrown key management tool. Traditional PAM solutions introduce audit logging and session recording features that capture user interactions with their servers and other infrastructure and/or centralized vaults that rotate keys and passwords for infrastructure every time a key is used. But this centralization can introduce performance bottlenecks, harm usability, and come with a significant price tag. Meanwhile, homegrown solutions are built from primitives provided by cloud providers or custom infrastructure-as-code solutions, and can be costly and tiresome to build out and maintain. 

We believe that organizations should apply Zero Trust principles to their most sensitive corporate resources, which naturally includes their infrastructure. That’s why we’re augmenting Cloudflare’s Zero Trust Network Access (ZTNA) service with Access to Infrastructure to support privileged access to sensitive infrastructure, and offering features that will look somewhat similar to those found in a PAM solution:

  • Access: Connect remote users to infrastructure targets via Cloudflare’s global network.

  • Authentication: Eliminate the management of credentials for servers, containers, clusters, and databases and replace them with SSO, MFA, and device posture. 

  • Authorization: Use policy-based access control to determine who can access what target, when, and under what role. 

  • Auditing: Provide command logs and session recordings to allow administrators to audit and replay their developers’ interactions with the organization’s infrastructure.

At Cloudflare, we are big believers that unified experiences produce the best security outcomes, and because of that, we are natively rebuilding each BastionZero feature into Cloudflare’s ZTNA service. Today, we will cover the recently-released feature for short-lived SSH access.

Secure Shell (SSH) and its security risks

SSH (Secure Shell) is a protocol that is commonly used by developers or system administrators to secure the connections used to remotely administer and manage (usually Linux/Unix) servers. SSH access to a server often comes with elevated privileges, including the ability to delete or exfiltrate data or to install or remove applications on the server. 

Modern enterprises can have tens, hundreds, or even thousands of SSH targets. Servers accessible via SSH can be targeted in cryptojacking or proxyjacking attacks. Manually tracking, rotating, and validating SSH credentials that grant access is a chore that is often left undone, which creates risks that these long-lived credentials could be compromised. There’s nothing stopping users from copying SSH credentials and sharing them with other users or transferring them to unauthorized devices.

Although many organizations will gate access to their servers to users that are inside their corporate network, this is no longer enough to protect against modern attackers. Today, the principles of Zero Trust demand that an organization also tracks who exactly is accessing their servers with SSH, and what commands they are running on those servers once they have access. In fact, the elevated privileges that come along with SSH access mean that compliance frameworks like SOC2, ISO27001, FedRAMP and others have criteria that require monitoring who has access with SSH and what exactly they are doing with that access. 

Introducing SSH with Access for Infrastructure

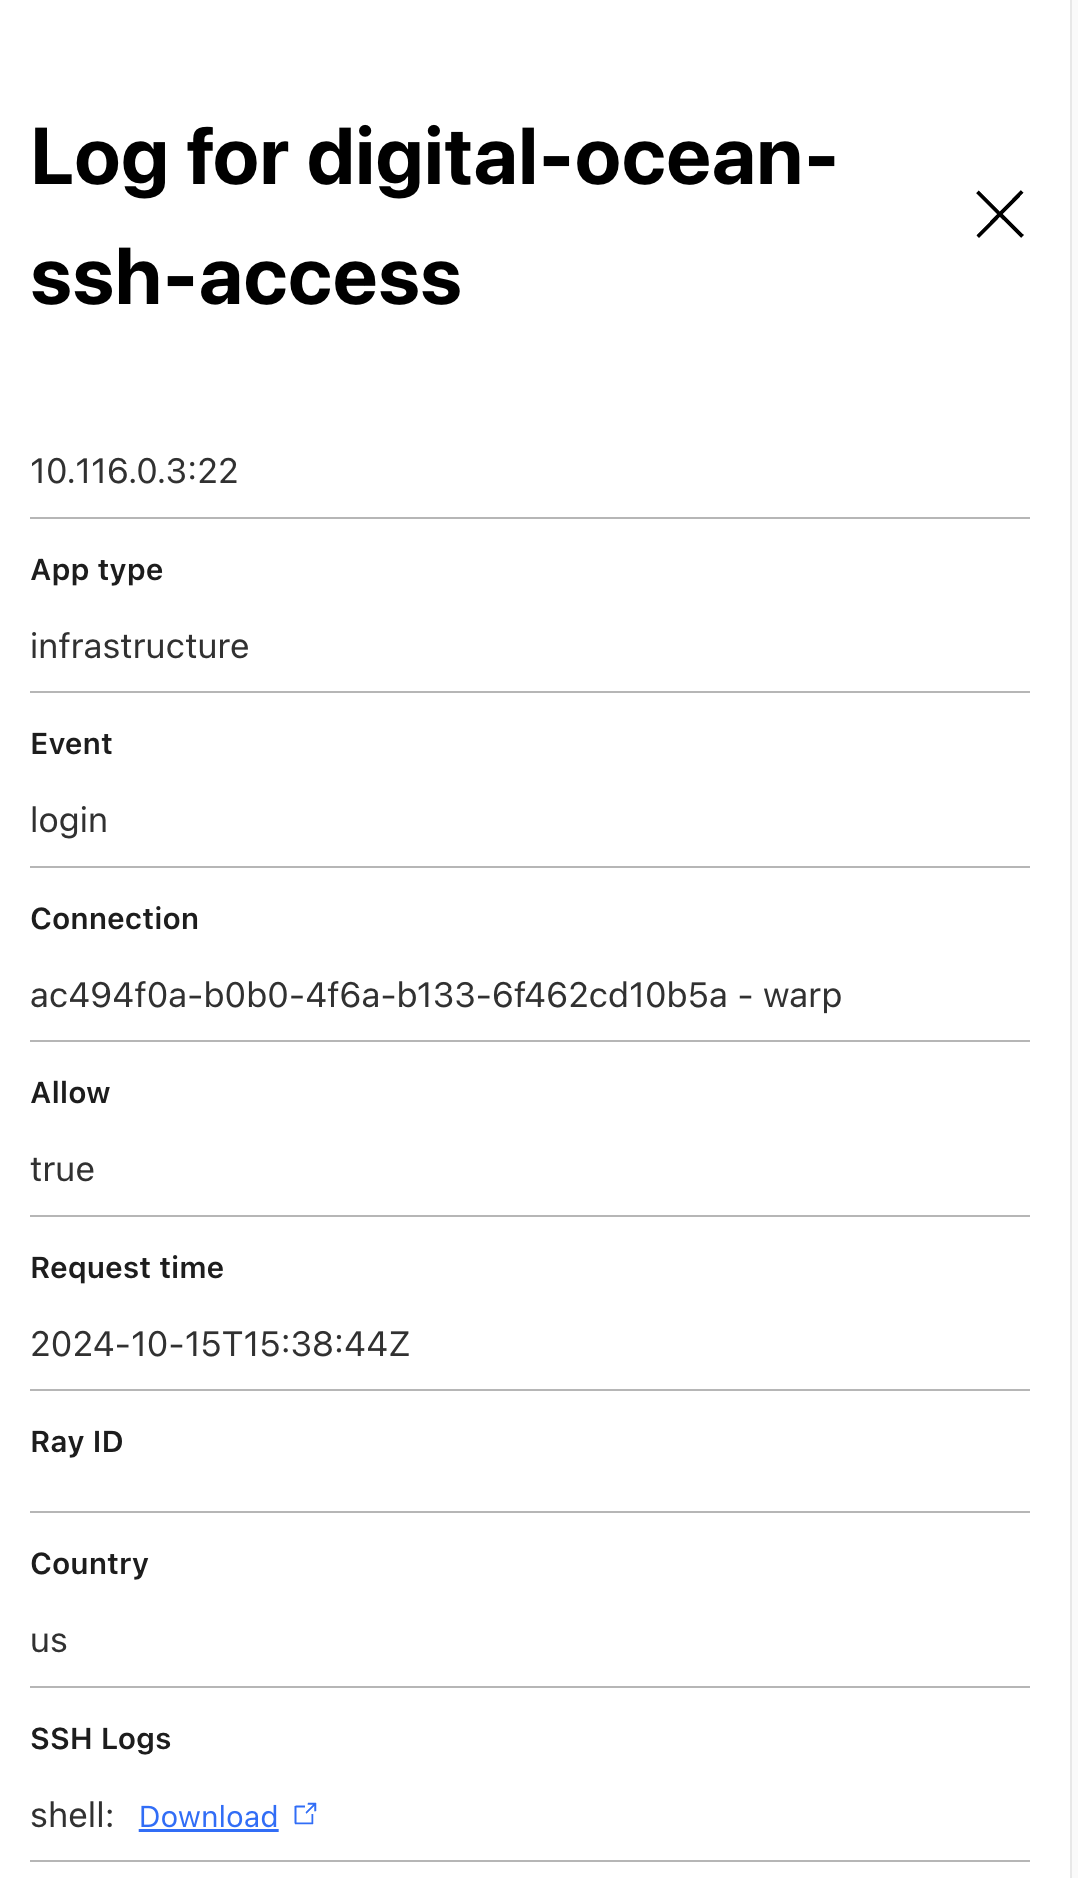
We’ve introduced SSH with Access for Infrastructure to provide customers with granular control over privileged access to servers via SSH. The feature provides improved visibility into who accessed what service and what they did during their SSH session, while also eliminating the risk and overhead associated with managing SSH credentials. Specifically, this feature enables organizations to:

  • Eliminate security risk and overhead of managing SSH keys and instead use short-lived SSH certificates issued by a Cloudflare-managed certificate authority (CA).

  • Author fine-grained policy to govern who can SSH to your servers and through which SSH user(s) they can log in as.

  • Monitor infrastructure access with Access and SSH command logs, supporting regulatory compliance and providing visibility in case of security breach.

  • Avoid changing end-user workflows. SSH with Access for Infrastructure supports whatever native SSH clients end users happen to be using. 

SSH with Access for Infrastructure is supported through one of the most common deployment models of Cloudflare One customers. Users can connect using our device client (WARP), and targets are made accessible using Cloudflare Tunnel (cloudflared or the WARP connector). This architecture allows customers with existing Cloudflare One deployments to enable this feature with little to no effort. The only additional setup will be configuring your target server to accept a Cloudflare SSH certificate.


Cloudflare One already offers multiple ways to secure organizations’ SSH traffic through network controls. This new SSH with Access for Infrastructure aims to incorporate the strengths of those existing solutions together with additional controls to authorize ports, protocols, and specific users as well as a much improved deployment workflow and audit logging capabilities.

Eliminating SSH credentials using an SSH CA

How does Access for Infrastructure eliminate your SSH credentials? This is done by replacing SSH password and SSH keys with an SSH Certificate Authority (CA) that is managed by Cloudflare. Generally speaking, a CA’s job is to issue certificates that bind an entity to an entity’s public key. Cloudflare’s SSH CA has a secret key that is used to sign certificates that authorize access to a target (server) via SSH, and a public key that is used by the target (server) to cryptographically validate these certificates. The public key for the SSH CA can be obtained by querying the Cloudflare API. And the secret key for the SSH CA is kept secure by Cloudflare and never exposed to anyone. 

To use SSH with Access for Infrastructure to grant access via SSH to a set of targets (i.e. servers), you need to instruct those servers to trust the Cloudflare SSH CA. Those servers will then grant access via SSH whenever they are presented with an SSH certificate that is validly signed by the Cloudflare SSH CA.

The same Cloudflare SSH CA is used to support SSH access for all of your developers and engineers to all your target servers. This greatly simplifies key management. You no longer need to manage long-lived SSH keys and passwords for individual end users, because access to targets with SSH is granted via certificates that are dynamically issued by the Cloudflare SSH CA. And, because the Cloudflare SSH CA issued short-lived SSH certificates that expire after 3 minutes, you also don’t have to worry about creating or managing long-lived SSH credentials that could be stolen by attackers. 

The 3-minute time window on the SSH certificate only applies to the time window during which the user has to authenticate to the target server; it does not apply to the length of the SSH session, which can be arbitrarily longer than 3 minutes. This 3-minute window was chosen because it was short enough to reduce the risk of security compromise and long enough to ensure that we don’t miss the time window of the user’s authentication to the server, especially if the user is on a slow connection.

Centrally managing policies down to the specific Linux user

One of the problems with traditional SSH is that once a user has an SSH key or password installed on a server, they will have access to that server forever — unless an administrator somehow remembers to remove their SSH key or password from the server in question. This leads to privilege creep, where too many people have standing access to too many servers, creating a security risk if an SSH key or password is ever stolen or leaked.

Instead, SSH with Access for Infrastructure allows you to centrally write policies in the Cloudflare dashboard specifying exactly what (set of) users has access to what (set of) servers. Users may be authenticated by SSO, MFA, device posture, location, and more, which provides better security than just authenticating them via long-lived SSH keys or passwords that could be stolen by attackers.

Moreover, the SSH certificates issued by the Cloudflare CA include a field called ValidPrinciples which indicates the specific Linux user (e.g. root, read-only, ubuntu, ec2-user) that can be assumed by the SSH connection. As such, you can write policies that specify the (set of) Linux users that a given (set of) end users may access on a given (set of) servers, as shown in the figure below. This allows you to centrally control the privileges that a given end user has when accessing a given target server. (The one caveat here is that the server must also be pre-configured to already know about the specific Linux user (e.g. root) that is specified in the policies and presented in the SSH certificate. Cloudflare is NOT managing the Linux users on your Linux servers.)

As shown below, you could write a policy that says users in Canada, the UK, and Australia that are authenticated with MFA and face recognition can access the root and ec2-user Linux users on a given set of servers in AWS.


How does Cloudflare capture SSH command logs?

Cloudflare captures SSH command logs because we built an SSH proxy that intercepts the SSH connections. The SSH proxy establishes one SSH connection between itself and the end user’s SSH client, and another SSH connection between itself and the target (server). The SSH proxy can therefore inspect the SSH commands and log them. 

SSH commands are encrypted at rest using a public key that the customer uploads via the Cloudflare API. Cloudflare cannot read SSH command logs at rest, but they can be extracted (in encrypted form) from the Cloudflare API and decrypted by the customer (who holds the corresponding private key). Instructions for uploading the encryption public key are available in our developer documentation.


How the SSH interception works under the hood

How does generic SSH work?

To understand how Cloudflare’s SSH proxy works, we first must review how a generic SSH connection is established.

First off, SSH runs over TCP, so to establish an SSH connection, we first need to complete a TCP handshake. Then, once the TCP handshake is complete, an SSH key exchange is needed to establish an ephemeral symmetric key between the client and the server that will be used to encrypt and authenticate their SSH traffic. The SSH key exchange is based on the server public key, also known as the hostkey. If you’ve ever used SSH, you’ve probably seen this message — that is the SSH server telling your SSH client to trust this hostkey for all future SSH interactions. (This is also known as TOFU or Trust On First Use.)


Finally, the client needs to authenticate itself to the server. This can be done using SSH passwords, SSH keys, or SSH certificates (as described above). SSH also has a mode called none, which means that the client does NOT need to authenticate itself to the server at all.

So how does Cloudflare’s SSH proxy work? 


To understand this, we note that whenever you set up SSH with Access for Infrastructure in the Cloudflare dashboard, you first need to create the set of targets (i.e. servers) that you want to make accessible via SSH. Targets can be defined by IP address or hostname. You then create an Access for Infrastructure application that captures the TCP ports (e.g. port 22) that SSH runs over for those targets, and write policies for those SSH connections, as we already described above and in our developer documentation.

This setup allows Cloudflare to know the set of IP addresses and ports for which it must intercept SSH traffic. Thus, whenever Cloudflare sees a TCP handshake with an IP address and port that must be intercepted, it sends traffic for that TCP connection to the SSH proxy. 

The SSH proxy leverages the client’s already authenticated identity from the WARP client, and enforces the configured Access for Infrastructure policies against it. If the policies do not allow the identity to connect to the target under the requested Linux user (e.g. root), the SSH proxy will reject the connection and log an Access denied event to the Access logs. Otherwise, if policies do allow the identity to connect, the the SSH proxy will establish the following two SSH connections: 

  1. SSH connection from SSH proxy to target

  2. SSH connection from end user’s SSH client (via Cloudflare’s WARP client) to SSH proxy

Let’s take a look at each of these SSH connections, and the cryptographic material used to set them up. 

To establish the SSH connection from SSH proxy to the target, the SSH proxy acts as a client in the SSH key exchange between itself and the target server. The handshake uses the target server’s hostkey to establish an ephemeral symmetric key between the client and the server that will encrypt and authenticate their SSH traffic. Next, the SSH proxy must authenticate itself to the target server. This is done by presenting the server with a short-lived SSH certificate, issued by the Cloudflare SSH CA, for the specified Linux user that is requested for this connection as we already described above. Because the target server has been configured to trust the Cloudflare SSH CA, the target server will be able to successfully validate the certificate and the SSH connection will be established.

To establish the SSH connection from the end-user’s SSH client to SSH proxy, the SSH proxy acts as a server in the SSH key exchange between itself and the end-user’s SSH client. 

To do this, the SSH proxy needs to inform the end user’s SSH client about the hostkey that will be used to establish this connection. But what hostkey should be used? We cannot use the same hostkey used by the target server, because that hostkey is the public key that corresponds to a private key that is known only to the target server, and not known to the SSH proxy. So, Cloudflare’s SSH proxy needs to generate its own hostkey. We don’t want the end user to randomly see warnings like the one shown below, so the SSH proxy should provide the same hostkey each time the user wants to access a given target server. But, if something does change with the hostkey of the target server, we do want the warning below to be shown. 


To achieve the desired behavior, the SSH proxy generates a hostkey and its corresponding private key by hashing together (a) a fixed secret value valid that associated with the customer account, along with (b) the hostkey that was provided by this target server (in the connection from SSH proxy to target server). This part of the design ensures that the end user only needs to see the TOFU notification the very first time it connects to the target server via WARP, because the same hostkey is used for all future connections to that target. And, if the hostkey of the target server does change as a result of a Monster-In-The-Middle attack, the warning above will be shown to the user.

Finally, during the SSH key exchange handshake from WARP client to SSH proxy, the SSH proxy informs that end user’s native SSH client that it is using none for client authentication. This means that the SSH client does NOT need to authenticate itself to the server at all. This part of the design ensures that the user need not enter any SSH passwords or store any SSH keys in its SSH configuration in order to connect to the target server via WARP. Also, this does not compromise security, because the SSH proxy has already authenticated the end user via Cloudflare’s WARP client and thus does not need to use the native SSH client authentication in the native SSH client.

Put this all together, and we have accomplished our goal of having end users authenticate to target servers without any SSH keys or passwords, using Cloudflare’s SSH CA instead. Moreover, we also preserve the desired behaviors of the TOFU notifications and warnings built into native SSH clients!

All the keys

Before we wrap up, let’s review the cryptographic keys you need in order to deploy SSH with Access for Infrastructure. There are two keys:

  1. Public key of the SSH CA. The private key of the SSH CA is only known to Cloudflare and not shared with anyone. The public key of the SSH CA is obtained from the Cloudflare API and must be installed on all your target servers. The same public key is used for all of your targets. This public key does not need to be kept secret.

  2. Private key for SSH command log encryption. To obtain logs of SSH commands, you need to generate a public-private key pair, and upload the public key to Cloudflare. The public key will be used to encrypt your SSH commands logs at REST. You need to keep the private key secret, and you can use it to decrypt your SSH command logs. 

That’s it! No other keys, passwords, or credentials to manage!

Try it out today

At Cloudflare, we are committed to providing the most comprehensive solution for ZTNA, which now also includes privileged access to sensitive infrastructure like servers accessed over SSH.

Organizations can now treat SSH like any other Access application and enforce strong MFA, device context, and policy-based access prior to granting user access. This allows organizations to consolidate their infrastructure access policies into their broader SSE or SASE architecture.

You can try out Access for Infrastructure today by following these instructions in our developer documentation. Access for Infrastructure is currently available free to teams of under 50 users, and at no extra cost to existing pay-as-you-go and Contract plan customers through an Access or Zero Trust subscription. Expect to hear about a lot more features from us as we continue to natively rebuild BastionZero’s technology into Cloudflare’s Access for Infrastructure service!

How to use interface VPC endpoints to meet your security objectives

Post Syndicated from Joaquin Manuel Rinaudo original https://aws.amazon.com/blogs/security/how-to-use-interface-vpc-endpoints-to-meet-your-security-objectives/

Amazon Virtual Private Cloud (Amazon VPC) endpoints—powered by AWS PrivateLink—enable customers to establish private connectivity to supported AWS services, enterprise services, and third-party services by using private IP addresses. There are three types of VPC endpoints: interface endpoints, Gateway Load Balancer endpoints, and gateway endpoints. An interface VPC endpoint, in particular, allows customers to design applications that connect to AWS services privately, including the more than 130 AWS services that are available over AWS PrivateLink. For a complete list of services that integrate with PrivateLink, see the documentation for VPC endpoints.

The decision regarding when to use interface VPC endpoints to further secure your AWS infrastructure depends on your need for additional security controls or your preferred architecture patterns. In this blog post, we present four security objectives that VPC endpoints help you achieve. It’s important to note that other non-security benefits, such as reduced latency and cost management, are not covered in this post. For more information on those benefits, see these topics:

Background

By default, network packets that originate in the AWS network with a destination on the AWS network (for example, public endpoints for AWS services) stay in the AWS network, except traffic to and from AWS China Regions. In addition, all data flowing across the AWS global network that interconnects AWS data centers and Regions is automatically encrypted at the physical layer before it leaves AWS secured facilities.

AWS PrivateLink VPC endpoints enable customers to further enhance the security posture of their applications by establishing private connectivity to supported AWS services, enterprise services, and third-party services by using a private IP address. You can find patterns for how to use the different types of endpoints in the Securely Access Services Over AWS PrivateLink whitepaper.

An interface VPC endpoint is a collection of one or more elastic network interfaces with private IP addresses. These endpoints can serve as an entry point for traffic destined to a supported AWS service in the same AWS Region as the VPC, without requiring an internet gateway, NAT device, VPN connection, AWS Direct Connect connection, or a public IP. Customers can then use interface VPC endpoints to help meet multiple security objectives, such as the following:

  1. Implement networks that are isolated from the internet
  2. Implement a data perimeter by using VPC endpoint policies
  3. Enable private connectivity to AWS service API endpoints for on-premises environments
  4. Align with specific compliance requirements

In the rest of this post, we’ll discuss each of these objectives in detail and how interface VPC endpoints can help you implement them.

Security objective 1: Implementing networks that are isolated from the internet

If you operate sensitive workloads, you might require that they run in private subnets that are isolated from the internet. In this scenario, the subnets in the network don’t have routes to an internet gateway and won’t be able to either send packets to the internet or receive packets from it.

In this case, you can use interface VPC endpoints to connect your VPC to AWS services in the same Region as if they were in your VPC, without configuring an internet gateway, NAT instance, or route tables. For information on how to configure a cross-Region VPC interface endpoint by using VPC peering, see this guidance.

Figure 1 shows an example architecture with an Amazon Elastic Compute Cloud (Amazon EC2) instance running in an isolated network and using interface VPC endpoints to send messages to Amazon Simple Queue Service (Amazon SQS).

Figure 1

Figure 1: Isolated subnet for EC2 server sending messages to Amazon SQS

Security objective 2: Implement a data perimeter using VPC endpoint policies

A data perimeter is a set of guardrails to help ensure that only your trusted identities are accessing trusted resources from expected networks. Learn more about data perimeters on AWS.

You can use VPC endpoint policies to implement a data perimeter by allowing access to only trusted entities and resources from your network, helping to prevent unintended access. This enables you to take advantage of the power of AWS Identity and Access Management (IAM) policy and flexibility to control access to your resources at a granular level.

In the VPC diagram in Figure 2, EC2 instance traffic flows out through a firewall endpoint, NAT gateway, and internet gateway to reach the S3 public API endpoint, remaining within the AWS network. However, this setup does not allow the implementation of a logical data perimeter to control the specific resources that the EC2 instance can access.

Figure 2

Figure 2: Before implementing a data perimeter

In contrast, in the diagram in Figure 3, you can see how VPC interface endpoints enable the use of VPC endpoint policies to enforce a data perimeter, such as only allowing certain S3 buckets to be accessed by the EC2 instance.

Figure 3

Figure 3: After implementing a data perimeter

For example, you can attach a policy, similar to the one below, to an Amazon S3 interface or gateway VPC endpoint to restrict access from the VPC to only S3 buckets that are owned by the same AWS Organizations organization. Make sure to replace <MY-ORG-ID> with your own information.

{
    "Version": "2012-10-17",
        "Statement": [
        {
            "Effect": "Allow",
            "Principal": "*",
            "Action": "s3:*",
            "Resource": "*",
            "Condition": { "StringEquals": { "aws:ResourceOrgID": <MY-ORG-ID>}}
        }
    ]
}

As a further example, the following policy shows how you can limit access to only trusted identities. You can attach this policy to an S3 interface VPC endpoint to permit access only to principals from your organization, to help mitigate the risk of unintended disclosure through non-corporate credentials. Make sure to replace <MY-ORG-ID> with your own information.

{    "Version": "2012-10-17",
        "Statement": [
        {
            "Effect": "Allow",
            "Principal": "*",
            "Action": "s3:*",
            "Resource": "*",
            "Condition": { "StringEquals": { "aws:PrincipalOrgID": "<MY-ORG-ID>"}}
        }
    ]
}

Finally, you can create resource policies for your resources to restrict access to only VPC interface endpoints. For example, you can use the following policy from our Amazon S3 User Guide for S3 buckets. Make sure to replace <MY-VPCE-ID> and <MY-BUCKET> with your own information.

 {  "Version": "2012-10-17",
        "Statement": [
        {
            "Effect": "Deny",
            "Principal": "*",
            "Action": "s3:*",
            "Resource": ["arn:aws:s3::<MY-BUCKET>", "arn:aws:s3::<MY-BUCKET>/*"]
            "Condition": { "StringNotEquals": { "aws:SourceVpce": "<MY-VPCE-ID>"}}
        }
    ]
}

For more information on the use of these condition keys and how to implement a data perimeter, see this blog post.

Security objective 3: Enable private connectivity to AWS service API endpoints for on-premises environments

You might be required to run private connectivity to AWS only from your on-premises environments, such as when your on-premises firewalls are configured to limit the connectivity to the internet, including AWS public endpoints.

In this case, you can use interface VPC endpoints with Direct Connect private virtual interfaces (VIFs) or Site-to-Site VPN to extend private connectivity to your on-premises networks. With this setup, you can also enforce data perimeter rules like those shown earlier in this post.

For example, customers can use interface VPC endpoints from Amazon CloudWatch agents running on on-premises servers to CloudWatch through a private connection, as demonstrated in this blog post.

In the diagram in Figure 4, we show how you can extend this approach to include other services, such as Amazon S3, in a single VPC setup. To implement this pattern, you need to set up conditional forwarding on your on-premises DNS resolver to forward queries for amazonaws.com to an Amazon Route 53 Resolver’s inbound endpoint IPs.

The flow in this scenario is as follows:

  1. The DNS query for your S3 endpoint from your on-premises host is routed to the locally configured on-premises DNS server.
  2. The on-premises DNS server performs conditional forwarding to an Amazon Route 53 inbound resolver endpoint IP address.
  3. The inbound resolver returns the IP address of the interface VPC endpoint, which allows the on-premises host to establish private connectivity through AWS VPN or AWS Direct Connect.
Figure 4

Figure 4: On-premises private connectivity to Amazon S3 and Amazon CloudWatch

You can extend this architecture to support a cross-Region and multi-VPC setup by using AWS Transit Gateway and Amazon Route 53 private hosted zones, as described in the Building a Scalable and Secure Multi-VPC AWS Network Infrastructure whitepaper. Keep in mind that a distributed VPC endpoint approach (one that uses one endpoint per VPC) will allow you to implement least-privilege policies in VPC endpoints. A centralized approach, while more cost-effective, can increase the complexity of maintaining least privilege in a single policy and increase the scope of impact of a security event.

Security objective 4: Align with specific compliance requirements

In certain cases, customers operating in industries such as financial services or healthcare need to maintain compliance with regulations or standards such as HIPAA, the EU-US Data Privacy Framework, and PCI DSS. Although all communication between instances and services hosted in AWS use the AWS private network, using an interface VPC endpoint can help prove to auditors that you’re applying a defense-in-depth approach. This approach includes designing your workloads to run in networks that are isolated from the internet or implementing additional conditions such as the example VPC endpoint policies shown earlier in this post.

You can use AWS Audit Manager to get started mapping your compliance requirements to industry and geographic frameworks, such as NIST SP 800-53 Rev. 5, FedRAMP, and PCI DSS, and to automate evidence collection for controls such as the use of VPC endpoints. If you also have custom compliance requirements, you can create your own custom controls by using the Configure Amazon Virtual Private Cloud (VPC) service endpoints core control in the AWS Audit Manager control library console.

If you want to know how the use of VPC endpoints can help you align with compliance requirements for your specific workload and require assistance beyond what is provided in the public documentation on the AWS Compliance Programs webpage, you can consult with AWS Security Assurance Services (AWS SAS). AWS SAS has expert consultants and advisors who can help you design your systems to achieve, maintain, and automate compliance in the cloud.

Conclusion

In this blog post, we presented four security objectives to consider when deciding whether to use AWS interface VPC endpoints. You can use this information when you design your architecture or create a threat model to help implement secure architectures for your AWS hosted workloads. If you want to learn more about AWS PrivateLink and interface endpoints, see the AWS PrivateLink documentation. If you’re interested in learning more about implementing data perimeter concepts by using VPC endpoints, we suggest this workshop.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Jonathan-Jenkyn

Jonathan-Jenkyn

Jonathan (“JJ”) is a Senior Security and Compliance Consultant with AWS Privacy, Security, and Assurance. He’s an active member of the People with Disabilities affinity group and has built several Amazon initiatives supporting charities and social responsibility causes. Since 1998, he has been involved in IT Security and Compliance at many levels, from implementation of cryptographic primitives to managing enterprise security governance. He also enjoys running, cycling, swimming, fundraising for the BHF and Ipswich Hospital Charity, and spending time with his wife and five children.

Andrea_Di_Fabio

Andrea Di Fabio

Andrea is a Senior Security Assurance Consultant with the AWS Professional Services Security Risk and Compliance team. In this role, Andrea uses a risk-based approach to help enterprise customers improve business agility as they operationalize the shared responsibility model throughout their technology transformation journey in AWS.

Zaur _Molotnikov

Zaur Molotnikov

Zaur is a Security Consultant at AWS Professional Services, specializing in complex application security code reviews for top global companies. With a passion for security management, he uses his expertise to help companies achieve robust protection measures. Outside work, Zaur enjoys the thrill of motorcycle riding and the creativity of working with power tools on construction projects.

Joaquin-Manuel-Rinaudo

Joaquin Manuel Rinaudo

Joaquin is a Principal Security Architect with AWS Professional Services. He is passionate about building solutions that help developers improve their software quality. Before joining AWS, he worked across multiple domains in the security industry, from mobile security to cloud- and compliance-related topics. In his free time, Joaquin enjoys spending time with family and reading science fiction novels

Summer 2024 SOC 1 report now available in Japanese, Korean, and Spanish

Post Syndicated from Brownell Combs original https://aws.amazon.com/blogs/security/summer-2024-soc-1-report-now-available-in-japanese-korean-and-spanish/

Japanese | Korean | Spanish

At Amazon Web Services (AWS), we continue to listen to our customers, regulators, and stakeholders to understand their needs regarding audit, assurance, certification, and attestation programs. We are pleased to announce that the AWS System and Organization Controls (SOC) 1 report is now available in Japanese, Korean, and Spanish. This translated report will help drive greater engagement and alignment with customer and regulatory requirements across Japan, Korea, Latin America, and Spain.

The Japanese, Korean, and Spanish language versions of the report do not contain the independent opinion issued by the auditors, but you can find this information in the English language version. Stakeholders should use the English version as a complement to the Japanese, Korean, or Spanish versions.

Going forward, the following reports in each quarter will be translated. Spring and Fall SOC 1 controls are included in the Spring and Fall SOC 2 reports, so this translation schedule will provide year-round coverage of the English versions.

Report Period covered
Spring SOC 2 April 1–March 31
Summer SOC 1 July 1–June 30
Fall SOC 2 October 1–September 30
Winter SOC 1 January 1–December 31

Customers can download the translated Summer 2024 SOC 1 reports in Japanese, Korean, and Spanish through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

The Summer 2024 SOC 1 report includes a total of 177 services in scope. For up-to-date information, including when additional services are added, see the AWS Services in Scope by Compliance Program webpage and choose SOC.

AWS strives to continuously bring services into scope of its compliance programs to help you meet your architectural and regulatory needs. Please reach out to your AWS account team if you have questions or feedback about SOC compliance.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.


Japanese version

Summer 2024 SOC 1 レポートの日本語、韓国語、スペイン語版の提供を開始

当社はお客様、規制当局、利害関係者の声に継続的に傾聴し、Amazon Web Services (AWS) における監査、保証、認定、認証プログラムに関するそれぞれのニーズを理解に努めています。この度、AWS System and Organization Controls (SOC) 1 レポートが、日本語、韓国語、スペイン語で利用可能になりました。この翻訳版のレポートは、日本、韓国、ラテンアメリカ、スペインのお客様および規制要件との連携と協力体制を強化するためのものです。

本レポートの日本語、韓国語、スペイン語版には監査人による独立した第三者の意見は含まれていませんが、英語版には含まれています。利害関係者は、日本語、韓国語、スペイン語版の補足として英語版を参照する必要があります。

今後、四半期ごとの以下のレポートで翻訳版が提供されます。SOC 1 統制は、Spring および Fall SOC 2 レポートに含まれるため、英語版と合わせ、1 年間のレポートの翻訳版すべてがこのスケジュールで網羅されることになります。

レポート 対象期間
春季SOC 2 4 月 1 日〜3 月 31 日
夏季SOC 1 7 月 1 日〜6 月 30 日
秋季SOC 2 10 月 1 日〜9 月 30 日
冬季SOC 1 1 月 1 日〜12 月 31 日

Summer 2024 SOC 1 レポートの日本語、韓国語、スペイン語版は AWS Artifact (AWS のコンプライアンスレポートをオンデマンドで入手するためのセルフサービスポータル) を使用してダウンロードできます。AWS マネジメントコンソール内の AWS Artifact にサインインするか、AWS Artifact の開始方法ページで詳細をご覧ください。

Summer 2024 SOC 1 レポートの対象範囲には合計 177 のサービスが含まれます。その他のサービスが追加される時期など、最新の情報については、コンプライアンスプログラムによる対象範囲内の AWS のサービスで [SOC] を選択してご覧いただけます。

AWS では、アーキテクチャおよび規制に関するお客様のニーズを支援するため、コンプライアンスプログラムの対象範囲に継続的にサービスを追加するよう努めています。SOC コンプライアンスに関するご質問やご意見については、担当の AWS アカウントチームまでお問い合わせください。

コンプライアンスおよびセキュリティプログラムに関する詳細については、AWS コンプライアンスプログラムをご覧ください。当社ではお客様のご意見・ご質問を重視しています。お問い合わせページより AWS コンプライアンスチームにお問い合わせください。


Korean version

2024년 하계 SOC 1 보고서가 한국어, 일본어, 스페인어로 제공됩니다.

Amazon은 고객, 규제 기관 및 이해관계자의 의견을 지속적으로 경청하여 Amazon Web Services (AWS)의 감사, 보증, 인증 및 증명 프로그램과 관련된 요구사항을 파악하고 있습니다. AWS System and Organization Controls(SOC) 1 보고서가 이제 한국어, 일본어, 스페인어로 제공됨을 알려 드립니다. 이 번역된 보고서는 일본, 한국, 중남미, 스페인 전역의 고객의 참여도를 높이고 규제 요건을 준수하는 데 도움이 될 것입니다.

보고서의 일본어, 한국어, 스페인어 버전에는 감사인의 독립적인 의견이 포함되어 있지 않지만, 영어 버전에서는 해당 정보를 확인할 수 있습니다. 이해관계자는 일본어, 한국어 또는 스페인어 버전을 보완하기 위해 영어 버전을 사용해야 합니다.

앞으로 분기마다 다음 보고서가 번역본으로 제공됩니다. SOC 1 통제 조치는 춘계 및 추계 SOC 2 보고서에 포함되어 있으므로, 이 일정은 영어 버전과 함께 모든 번역된 언어로 연중 내내 제공됩니다.

보고 대상 기간
춘계 SOC 2 4월 1일~3월 31일
하계 SOC 1 7월 1일~6월 30일
추계 SOC 2 10월 1일~9월 30일
동계 SOC 1 1월 1일~12월 31일

고객은 AWS 규정 준수 보고서를 필요할 때 이용할 수 있는 셀프 서비스 포털인 AWS Artifact를 통해 일본어, 한국어, 스페인어로 번역된 2024년 하계 SOC 1 보고서를 다운로드할 수 있습니다. AWS Management Console의 AWS Artifact에 로그인하거나 Getting Started with AWS Artifact(AWS Artifact 시작하기)에서 자세한 내용을 알아보세요.

2024년 하계 SOC 1 보고서에는 총 177개의 서비스가 포함됩니다. 추가 서비스가 추가되는 시기 등의 최신 정보는 AWS Services in Scope by Compliance Program(규정 준수 프로그램별 범위 내 AWS 서비스)에서 SOC를 선택하세요.

AWS는 고객이 아키텍처 및 규제 요구사항을 충족할 수 있도록 지속적으로 서비스를 규정 준수 프로그램의 범위에 포함시키기 위해 노력하고 있습니다. SOC 규정 준수에 대한 질문이나 피드백이 있는 경우 AWS Account 팀에 문의하시기 바랍니다.

규정 준수 및 보안 프로그램에 대한 자세한 내용은 AWS 규정 준수 프로그램을 참조하세요. 언제나 그렇듯이 AWS는 여러분의 피드백과 질문을 소중히 여깁니다. 문의하기 페이지를 통해 AWS 규정 준수 팀에 문의하시기 바랍니다.


Spanish version

El informe SOC 1 verano 2024 se encuentra disponible actualmente en japonés, coreano y español

Seguimos escuchando a nuestros clientes, reguladores y partes interesadas para comprender sus necesidades en relación con los programas de auditoría, garantía, certificación y acreditación en Amazon Web Services (AWS). Nos enorgullece anunciar que el informe de controles de sistema y organización (SOC) 1 de AWS se encuentra disponible en japonés, coreano y español. Estos informes traducidos ayudarán a impulsar un mayor compromiso y alineación con los requisitos normativos y de los clientes en Japón, Corea, Latinoamérica y España.

Estas versiones del informe en japonés, coreano y español no contienen la opinión independiente emitida por los auditores, pero se puede acceder a esta información en la versión en inglés del documento. Las partes interesadas deben usar la versión en inglés como complemento de las versiones en japonés, coreano y español.

De aquí en adelante, los siguientes informes trimestrales estarán traducidos. Dado que los controles SOC 1 se incluyen en los informes de primavera y otoño de SOC 2, esta programación brinda una cobertura anual para todos los idiomas traducidos cuando se la combina con las versiones en inglés.

de AWS IAM Período cubierto
SOC 2 primavera Del 1 de abril al 31 de marzo
SOC 1 verano Del 1 de julio al 30 de junio
SOC 2 otoño Del 1 de octubre al 30 de septiembre
SOC 1 invierno Del 1 de enero al 31 de diciembre

Los clientes pueden descargar los informes SOC 1 verano 2024 traducidos al japonés, coreano y español a través de AWS Artifact, un portal de autoservicio para el acceso bajo demanda a los informes de conformidad de AWS. Inicie sesión en AWS Artifact mediante la Consola de administración de AWS u obtenga más información en Introducción a AWS Artifact.

El informe SOC 1 verano 2024 incluye un total de 177 servicios que se encuentran dentro del alcance. Para acceder a información actualizada, que incluye novedades sobre cuándo se agregan nuevos servicios, consulte los Servicios de AWS en el ámbito del programa de conformidad y seleccione SOC.

AWS se esfuerza de manera continua por añadir servicios dentro del alcance de sus programas de conformidad para ayudarlo a cumplir con sus necesidades de arquitectura y regulación. Si tiene alguna pregunta o sugerencia sobre la conformidad de los SOC, no dude en comunicarse con su equipo de cuenta de AWS.

Para obtener más información sobre los programas de conformidad y seguridad, consulte los Programas de conformidad de AWS. Como siempre, valoramos sus comentarios y preguntas; de modo que no dude en comunicarse con el equipo de conformidad de AWS a través de la página Contacte con nosotros.
 

Brownell Combs

Brownell Combs
Brownell is a Compliance Program Manager at AWS, where he leads multiple security and privacy initiatives. Brownell holds a Master’s Degree in Computer Science from the University of Virginia and a Bachelor’s Degree in Computer Science from Centre College. He has over 20 years of experience in information technology risk management and CISSP, CISA, CRISC, and GIAC GCLD certifications.

Rodrigo Fiuza

Rodrigo Fiuza
Rodrigo is a Security Audit Manager at AWS, based in São Paulo. He leads audits, attestations, certifications, and assessments across Latin America, the Caribbean, and Europe. Rodrigo has worked in risk management, security assurance, and technology audits for the past 12 years.

Paul Hong

Paul Hong
Paul is a Compliance Program Manager at AWS. He leads multiple security, compliance, and training initiatives within AWS and has over 10 years of experience in security assurance. Paul is a CISSP, CEH, and CPA, and holds a Masters of Accounting Information Systems and a Bachelors of Business Administration from James Madison University, Virginia.

Hwee Hwang

Hwee Hwang
Hwee is an Audit Specialist at AWS based in Seoul, South Korea. Hwee is responsible for third-party and customer audits, certifications, and assessments in Korea. Hwee previously worked in security governance, risk, and compliance and is laser focused on building customers’ trust and providing them assurance in the cloud.

Tushar Jain

Tushar Jain
Tushar is a Compliance Program Manager at AWS, where he leads multiple security, compliance, and training initiatives. He holds a Master of Business Administration degree from Indian Institute of Management and a Bachelor of Technology in Electronics and Telecommunication Engineering degree from Marathwada University. He has over 12 years of experience in information security and holds CCSK and CSXF certifications.

Eun Jin Kim

Eun Jin Kim
Eun Jin is a security assurance professional working as the Audit Program Manager at AWS. She mainly leads compliance programs in South Korea for the financial sector. She has more than 25 years of experience and holds a Master’s Degree in Management Information Systems from Carnegie Mellon University and a Master’s Degree in Law from George Mason University.

Michael Murphy

Michael Murphy
Michael is a Compliance Program Manager at AWS, where he leads multiple security and privacy initiatives. Michael has 12 years of experience in information security. He holds a Master’s Degree and a Bachelor’s Degree in Computer Engineering from Stevens Institute of Technology. He also holds CISSP, CRISC, CISA, and CISM certifications.

Nathan Samuel

Nathan Samuel
Nathan is a Compliance Program Manager at AWS, where he leads multiple security and privacy initiatives. Nathan has a Bachelor’s of Commerce degree from the University of the Witwatersrand, South Africa. He has 21 years’ experience in security assurance and holds the CISA, CRISC, CGEIT, CISM, CDPSE, and Certified Internal Auditor certifications.

Seul Un Sung

Seul Un Sung
Seul Un is a Security Assurance Audit Program Manager at AWS, where she has been leading South Korea audit programs, including K-ISMS and RSEFT, for the past 4 years. She has a Bachelor’s of Information Communication and Electronic Engineering degree from Ewha Womans University and has 14 years of experience in IT risk, compliance, governance, and audit, and holds the CISA certification.

Hidetoshi Takeuchi

Hidetoshi Takeuchi
Hidetoshi is a Senior Audit Program Manager at AWS, based in Japan, leading Japan and India security certification and authorization programs. Hidetoshi has led information technology, cyber security, risk management, compliance, security assurance, and technology audits for the past 28 years and holds the CISSP certifications.

ryan wilks

Ryan Wilks
Ryan is a Compliance Program Manager at AWS, where he leads multiple security and privacy initiatives. Ryan has 13 years of experience in information security. He has a Bachelor of Arts degree from Rutgers University and holds ITIL, CISM, and CISA certifications.

Managing identity source transition for AWS IAM Identity Center

Post Syndicated from Xiaoxue Xu original https://aws.amazon.com/blogs/security/managing-identity-source-transition-for-aws-iam-identity-center/

AWS IAM Identity Center manages user access to Amazon Web Services (AWS) resources, including both AWS accounts and applications. You can use IAM Identity Center to create and manage user identities within the Identity Center identity store or to connect seamlessly to other identity sources.

Organizations might change the configuration of their identity source in IAM Identity Center for various reasons. These include switching identity providers (IdPs), expanding their identity footprint, adopting new features, and so on. These transitions can disrupt user access and require planning to minimize downtime.

In this blog post, we walk you through the process of switching from one identity source to another and provide sample code that you can use to assist with the transition.

Background

The identity source configured in IAM Identity Center determines where users and groups are created and managed. Each organization can connect to only one identity source at a time. Identity Center supports three main identity source options:

  1. Identity Center directory: This is the default identity store for IAM Identity Center. You can use it to directly create and administer your users and groups within Identity Center without relying on an external provider.
  2. Active Directory: You can configure integration with an on-premises Active Directory or with AWS Managed Microsoft AD using AWS Directory Service. This integration enables you to use your existing Active Directory identities and group memberships.
  3. External IdP: You can continue using your current third-party IdPs that support SAML 2.0, such as Okta Universal Directory or Microsoft Entra ID (formerly Azure AD).

Understanding these identity source options can help you choose the source that best fits your user management needs based on your existing infrastructure and authentication requirements.

Figure 1 explains the flow of users and groups accessing AWS resources. This access is granted through the following:

Figure 1: Granting access to AWS resources for users and groups managed by an identity source in IAM Identity Center

Figure 1: Granting access to AWS resources for users and groups managed by an identity source in IAM Identity Center

When you change the identity source, the work required varies depending on the original and new sources. AWS documentation details these considerations. In minimal impact scenarios, assignments remain intact, although you need to force password resets or verify correct assertions from the new source. More disruptive scenarios delete users, groups, and their assignments. In those scenarios, you need to restore the deleted entries after changing the identity source.

Sample deployment

This deployment covers permission sets and application assignments’ backup and restore. These scripts associate assignments with unique user attributes such as UserName, and group attributes such as DisplayName. Attributes that might change during the user and group restoration process, such as UserId and GroupId, aren’t used.

What isn’t covered includes users, groups, permission sets, and applications backup and restore.

  • Users and groups backup and restore aren’t covered because they depend heavily on the format of the source and target IdPs.
  • Because we’re working with identity source switching, the permission sets will remain unchanged and applications will not be deleted.
  • If you’re changing IdPs as part of an AWS Region , the IAM Identity Center instance will be deleted. The applications and permission sets will be deleted in addition to assignments. In this case, you must redeploy the applications. See How to automate the review and validation of permissions for users and groups in AWS IAM Identity Center for information about backing up permission sets.

The sample scripts and detailed steps are available on GitHub.

Note: This solution is available in the GitHub aws-samples repository. You can report bugs or make feature requests through GitHub Issues. The builders of this solution can help with GitHub issues. Enterprise Support customers can reach out to their Technical Account Manager (TAM) for further questions or feature requests.

Walkthrough

In this section, we walk you through the process of transitioning to a new identity source in IAM Identity Center.

Step 1: Backup users, groups, and assignments from the current identity source

This step is critical to preserve users’ information and their associated access scope.

How to backup users and groups:

Note: For some external IdPs, there are native integrations with Active Directory, such as Okta AD integration and Ping One AD Connect. You can set up a native integration and sync users and groups data without needing to backup and restore that data.

Assignments can be backed up by running the backup.py file from GitHub. Replace <IDC_STORE_ID> with your Identity Store ID (it looks like d-1234567890), and replace <IDC_ARN> with the Amazon Resource Name (ARN) for your IAM Identity Center instance.

python3 backup.py --idc-id <IDC_STORE_ID> --idc-arn <IDC_ARN>

This script uses both IAM Identity Center APIs and Identity Store APIs as shown in Figure 2 that generates permission set assignments backup files (UserAssignments.json and GroupAssignments.json) and an application assignments backup file (AppAssignments.json).

Figure 2: APIs used for backing up assignments

Figure 2: APIs used for backing up assignments

Step 2: Restore and validate the backed-up users and groups in the target identity source

The target will become the new authoritative identity source. When done, verify that the group memberships and attributes have been correctly transferred.

  • If the target is an IAM Identity Center directory, use APIs such as CreateUser, CreateGroup, and CreateGroupMembership to restore from the previous backup file.
  • If the target is Active Directory or an external IdP, use the corresponding native import features or integration tools to restore.

Step 3: Configure IAM Identity Center to connect to the new identity source and synchronize users and groups

Update your IAM Identity Center configuration to point to the new source. If applicable, use tools such as configurable AD sync or automatic provisioning with SCIM to synchronize your restored identities.

WARNING: While the directory is being rebuilt, your users will not have access to AWS accounts or applications through IAM Identity Center until all assignments are restored in Step 4.

Step 4: Restore assignments to users and groups in the new identity source

The APIs used to restore assignments are as shown in Figure 3.

Figure 3: APIs used for restoring assignments

Figure 3: APIs used for restoring assignments

Assignments can be restored by running the restore.py file from GitHub. Replace <NEW_IDC_STORE_ID> with your newly configured Identity Store ID (it looks like d-1234567890) and replace <IDC_ARN> with the ARN for your IAM Identity Center instance.

python3 restore.py --idc-id <NEW_IDC_STORE_ID> --idc-arn <IDC_ARN>

This script uses the APIs illustrated in Figure 2 and picks up backup files (UserAssignments.json, GroupAssignments.json, and AppAssignments.json) from Step 1 by default. Account permission set assignment results are automatically retrieved five times using exponential backoff. If the result is other than SUCCEEDED after five retries, the principal ID will be marked as failed and exported in error logs.

Note: For AWS managed applications that maintain a separate identity source, using the CreateApplicationAssignments API to restore application assignments will not preserve user access. These applications typically have dependencies on the original identity source ID, or dependencies on UserId and GroupId from the original identity source. This dependency is represented by importing users or groups from IAM Identity Center during the AWS managed application creation process. Example AWS managed applications include Amazon SageMaker Studio and Amazon Q Developer. These applications must be restored on a case-by-case basis and can require redeployment of the application.

Step 5: Validate user access using the new identity source

Make sure that users can still access the expected accounts and applications.

Conclusion

Transitioning your identity source in IAM Identity Center requires careful planning and implementation. This post outlined the steps to manage this transition. By following these steps, you can streamline the transition process, providing a smooth and efficient transfer of user access with minimal downtime. To get started, see the GitHub repository. For related posts, visit the AWS Security Blog channel and search for IAM Identity Center.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Xiaoxue Xu
Xiaoxue Xu

Xiaoxue Xu is a Solutions Architect for AWS based in Toronto. She primarily works with Financial Services customers to help secure their workload and design scalable solutions on the AWS Cloud.
Kanwar Bajwa
Kanwar Bajwa

Kanwar Bajwa is a Principal Technical Account Manager at AWS who works with customers to optimize their use of AWS services and achieve their business objectives.
Yee Fei Ooi
Yee Fei Ooi

Yee Fei is a Solutions Architect supporting independent software vendor (ISV) customers in Singapore and is part of the Containers TFC. She enjoys helping her customers to grow their businesses and build solutions that automate, innovate, and improve efficiency.

2024 H1 IRAP report is now available on AWS Artifact for Australian customers

Post Syndicated from Patrick Chang original https://aws.amazon.com/blogs/security/2024-h1-irap-report-is-now-available-on-aws-artifact-for-australian-customers/

Amazon Web Services (AWS) is excited to announce that a new Information Security Registered Assessors Program (IRAP) report (2024 H1) is now available through AWS Artifact. An independent Australian Signals Directorate (ASD) certified IRAP assessor completed the IRAP assessment of AWS in August 2024.

The new IRAP report includes an additional seven AWS services that are now assessed at the PROTECTED level under IRAP. This brings the total number of services assessed at the PROTECTED level to 158.

The following are the seven newly assessed services:

For the full list of services, see the IRAP tab on the AWS Services in Scope by Compliance Program page.

Many Australian customers are looking to experiment with how generative AI applications can help them better serve the Australian public. Customers can use two of the newly assessed services—Amazon Bedrock and Amazon DataZone—to help align with their governance, sovereignty, and security requirements up to the PROTECTED level:

  • Amazon Bedrock is a fully managed service that offers a choice of high-performing large language models (LLMs) and other foundation models (FMs) from leading AI companies like AI21 Labs, Anthropic, Cohere, Meta, Mistral AI, Stability AI, as well as Amazon through a single API. Amazon Bedrock also provides a broad set of capabilities customers need to build generative AI applications with security, privacy, and responsible AI.
  • Amazon DataZone is a data management service that makes it faster and simpler for customers to catalog, discover, share, and govern data stored across AWS, on premises, and third-party sources.

AWS has developed an IRAP documentation pack to help Australian customers and their partners to plan, architect, and assess risk for their workloads when they use AWS Cloud services.

We developed this pack in accordance with the Australian Cyber Security Centre (ACSC) Cloud Security Guidance and Cloud Assessment and Authorisation framework, which addresses guidance within the Australian Government’s Information Security Manual (ISM, September 2023 version), the Department of Home Affairs’ Protective Security Policy Framework (PSPF), and the Digital Transformation Agency’s Secure Cloud Strategy.

The IRAP pack on AWS Arti­­fact also includes newly updated versions of the AWS Consumer Guide and the whitepaper Reference Architectures for ISM PROTECTED Workloads in the AWS Cloud.

Reach out to your AWS representatives to let us know which additional services you would like to see in scope for upcoming IRAP assessments. We strive to bring more services into scope at the PROTECTED level under IRAP to support your requirements.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Patrick Chang
Patrick Chang

Patrick is the APJ Audit Lead based in Sydney. He leads security audits, certifications, and compliance programs across the APJ region. He is a technology risk and audit professional with over a decade of experience. He is passionate about delivering assurance programs that build trust with customers and provide them assurance on cloud security.

AWS renews its GNS Portugal certification for classified information with 66 services

Post Syndicated from Daniel Fuertes original https://aws.amazon.com/blogs/security/aws-renews-its-gns-portugal-certification-for-classified-information-with-66-services/

Amazon Web Services (AWS) announces that it has successfully renewed the Portuguese GNS (Gabinete Nacional de Segurança, National Security Cabinet) certification in the AWS Regions and edge locations in the European Union. This accreditation confirms that AWS cloud infrastructure, security controls, and operational processes adhere to the stringent requirements set forth by the Portuguese government for handling classified information at the National Reservado level (equivalent to the NATO Restricted level).

The GNS certification is based on the NIST SP800-53 Rev. 5 and CSA CCM v4 frameworks. It demonstrates the AWS commitment to providing the most secure cloud services to public-sector customers, particularly those with the most demanding security and compliance needs. By achieving this certification, AWS has demonstrated its ability to safeguard classified data up to the Reservado (Restricted) level, in accordance with the Portuguese government’s rigorous security standards.

AWS was evaluated by an authorized and independent third-party auditor, Adyta Lda, and by the Portuguese GNS itself. With the GNS certification, AWS customers in Portugal, including public sector organizations and defense contractors, can now use the full extent of AWS cloud services to handle national restricted information. This enables these customers to take advantage of AWS scalability, reliability, and cost-effectiveness, while safeguarding data in alignment with GNS standards.

We’re happy to announce the addition of 40 services to the scope of our GNS certification, for a new total of 66 services in scope. To view the complete list of services included in the scope, see the AWS Services in Scope by Compliance Program – GNS National Restricted Certification page.

The Certificate of Compliance illustrating the compliance status of AWS is available on the GNS Certifications page and through AWS Artifact.

For more information about GNS, see the AWS Compliance page GNS National Restricted Certification.

If you have feedback about this post, submit comments in the Comments section below.
 

Daniel Fuertes
Daniel Fuertes

Daniel is a Security Audit Program Manager at AWS, based in Madrid, Spain. Daniel leads multiple security audits, attestations, and certification programs in Spain, Portugal, and other EMEA countries. Daniel has ten years of experience in security assurance and compliance, including previous experience as an auditor for the PCI DSS security framework. He also holds the CISSP, PCIP, and ISO 27001 Lead Auditor certifications.

AWS achieves HDS certification in four additional AWS Regions

Post Syndicated from Janice Leung original https://aws.amazon.com/blogs/security/aws-achieves-hds-certification-in-four-additional-aws-regions/

Amazon Web Services (AWS) is pleased to announce that four additional AWS Regions—Asia Pacific (Hong Kong), Asia Pacific (Osaka), Asia Pacific (Hyderabad), and Israel (Tel Aviv)—have been granted the Health Data Hosting (Hébergeur de Données de Santé, HDS) certification, increasing the scope to 24 global AWS Regions.

The Agence du Numérique en Santé (ANS), the French governmental agency for health, introduced the HDS certification to strengthen the security and protection of personal health data. By achieving this certification, AWS demonstrates our continuous commitment to adhere to the heightened expectations for cloud service providers.

The following 24 Regions are in scope for this certification:

  • US East (N. Virginia)
  • US East (Ohio)
  • US West (N. California)
  • US West (Oregon)
  • Asia Pacific (Hong Kong)
  • Asia Pacific (Hyderabad)
  • Asia Pacific (Jakarta)
  • Asia Pacific (Mumbai)
  • Asia Pacific (Osaka)
  • Asia Pacific (Seoul)
  • Asia Pacific (Singapore)
  • Asia Pacific (Sydney)
  • Asia Pacific (Tokyo)
  • Canada (Central)
  • Europe (Frankfurt)
  • Europe (Ireland)
  • Europe (London)
  • Europe (Milan)
  • Europe (Paris)
  • Europe (Stockholm)
  • Europe (Zurich)
  • Middle East (UAE)
  • Israel (Tel Aviv)
  • South America (São Paulo)

The HDS certification demonstrates that AWS provides a framework for technical and governance measures to secure and protect personal health data according to HDS requirements. Our customers who handle personal health data can continue to manage their workloads in HDS-certified Regions with confidence.

Independent third-party auditors evaluated and certified AWS on September 3, 2024. The HDS Certificate of Compliance demonstrating AWS compliance status is available on the Agence du Numérique en Santé (ANS) website and AWS Artifact. AWS Artifact is a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

For up-to-date information, including when additional Regions are added, visit the AWS Compliance Programs page and choose HDS.

AWS strives to continuously meet your architectural and regulatory needs. If you have questions or feedback about HDS compliance, reach out to your AWS account team.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below.

Author

Janice Leung
Janice is a Security Assurance Program Manager at AWS based in New York. She leads various commercial security certifications, within the automobile, healthcare, and telecommunications sectors across Europe. In addition, she leads the AWS infrastructure security program worldwide. Janice has over 10 years of experience in technology risk management and audit at leading financial services and consulting company.

Tea Jioshvili

Tea Jioshvili
Tea is a Security Assurance Manager at AWS, based in Berlin, Germany. She leads various third-party audit programs across Europe. She previously worked in security assurance and compliance, business continuity, and operational risk management in the financial industry for multiple years.

2024 ISO and CSA STAR certificates now available with three additional services

Post Syndicated from Atulsing Patil original https://aws.amazon.com/blogs/security/2024-iso-and-csa-star-certificates-now-available-with-three-additional-services/

Amazon Web Services (AWS) successfully completed an onboarding audit with no findings for ISO 9001:2015, 27001:2022, 27017:2015, 27018:2019, 27701:2019, 20000-1:2018, and 22301:2019, and Cloud Security Alliance (CSA) STAR Cloud Controls Matrix (CCM) v4.0. Ernst and Young CertifyPoint auditors conducted the audit and reissued the certificates on July 22, 2024. The objective of the audit was to assess the level of compliance with the requirements of the applicable international standards.

During the audit, we added the following three AWS services to the scope of the certification:

For a full list of AWS services that are certified under ISO and CSA Star, see the AWS ISO and CSA STAR Certified page. Customers can also access the certifications in the AWS Management Console through AWS Artifact.

If you have feedback about this post, submit comments in the Comments section below.

Atul Patil

Atulsing Patil
Atulsing is a Compliance Program Manager at AWS. He has 27 years of consulting experience in information technology and information security management. Atulsing holds a master of science in electronics degree and professional certifications such as CCSP, CISSP, CISM, CDPSE, ISO 27001 Lead Auditor, HITRUST CSF, Archer Certified Consultant, and AWS CCP.

Nimesh Ravas

Nimesh Ravasa
Nimesh is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Nimesh has 15 years of experience in information security and holds CISSP, CDPSE, CISA, PMP, CSX, AWS Solutions Architect – Associate, and AWS Security Specialty certifications.

Chinmaee Parulekar

Chinmaee Parulekar
Chinmaee is a Compliance Program Manager at AWS. She has 5 years of experience in information security. Chinmaee holds a master of science degree in management information systems and professional certifications such as CISA.

Summer 2024 SOC report now available with 177 services in scope

Post Syndicated from Brownell Combs original https://aws.amazon.com/blogs/security/summer-2024-soc-report-now-available-with-177-services-in-scope/

We continue to expand the scope of our assurance programs at Amazon Web Services (AWS) and are pleased to announce that the Summer 2024 System and Organization Controls (SOC) 1 report is now available. The report covers 177 services over the 12-month period of July 1, 2023–June 30, 2024, so that customers have a full year of assurance with the report. This report demonstrates our continuous commitment to adhere to the heightened expectations for cloud service providers.

Going forward, we will issue SOC reports covering a 12-month period each quarter as follows:

Report Period covered
Spring SOC 1, 2, and 3 April 1–March 31
Summer SOC 1 July 1–June 30
Fall SOC 1, 2, and 3 October 1–September 30
Winter SOC 1 January 1–December 31

Customers can download the Summer 2024 SOC report through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

AWS strives to continuously bring services into the scope of its compliance programs to help you meet your architectural and regulatory needs. If you have questions or feedback about SOC compliance, reach out to your AWS account team.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

If you have feedback about this post, submit comments in the Comments section below.

Brownell Combs
Brownell Combs

Brownell is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Brownell holds a master of science degree in computer science from University of Virginia and a bachelor of science degree in computer science from Centre College. He has over 20 years of experience in IT risk management and CISSP, CISA, CRISC, and GIAC GCLD certifications.
Paul Hong
Paul Hong

Paul is a Compliance Program Manager at AWS. He leads multiple security, compliance, and training initiatives within AWS, and has 10 years of experience in security assurance. Paul holds CISSP, CEH, and CPA certifications. He has a master’s degree in accounting information systems and a bachelor’s degree in business administration from James Madison University, Virginia.
Tushar Jain
Tushar Jain

Tushar is a Compliance Program Manager at AWS. He leads multiple security, compliance, and training initiatives within AWS. Tushar holds a master of business administration from Indian Institute of Management Shillong, and a bachelor of technology in electronics and telecommunication engineering from Marathwada University. He has over 12 years of experience in information security and holds CCSK and CSXF certifications.
Michael Murphy
Michael Murphy

Michael is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Michael has 12 years of experience in information security. He holds a master’s degree and a bachelor’s degree in computer engineering from Stevens Institute of Technology. He also holds CISSP, CRISC, CISA, and CISM certifications.
Nathan Samuel
Nathan Samuel

Nathan is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Nathan has a bachelor of commerce degree from the University of the Witwatersrand, South Africa, and has over 21 years of experience in security assurance. He holds the CISA, CRISC, CGEIT, CISM, CDPSE, and Certified Internal Auditor certifications.
ryan wilks
Ryan Wilks

Ryan is a Compliance Program Manager at AWS. He leads multiple security and privacy initiatives within AWS. Ryan has 13 years of experience in information security. He has a bachelor of arts degree from Rutgers University and holds ITIL, CISM, and CISA certifications.

Spring 2024 SOC 2 report now available in Japanese, Korean, and Spanish

Post Syndicated from Brownell Combs original https://aws.amazon.com/blogs/security/spring-2024-soc-2-report-now-available-in-japanese-korean-and-spanish/

Japanese | Korean | Spanish

At Amazon Web Services (AWS), we continue to listen to our customers, regulators, and stakeholders to understand their needs regarding audit, assurance, certification, and attestation programs. We are pleased to announce that the AWS System and Organization Controls (SOC) 2 report is now available in Japanese, Korean, and Spanish. This translated report will help drive greater engagement and alignment with customer and regulatory requirements across Japan, Korea, Latin America, and Spain.

The Japanese, Korean, and Spanish language versions of the report do not contain the independent opinion issued by the auditors, but you can find this information in the English language version. Stakeholders should use the English version as a complement to the Japanese, Korean, or Spanish versions.

Going forward, the following reports in each quarter will be translated. Spring and Fall SOC 1 controls are included in the Spring and Fall SOC 2 reports, so this translation schedule will provide year-round coverage of the English versions.

  • Spring SOC 2 (April 1 – March 31)
  • Summer SOC 1 (July 1 – June 30)
  • Fall SOC 2 (October 1 – September 30)
  • Winter SOC 1 (January 1 – December 31)

Customers can download the translated Spring 2024 SOC 2 reports in Japanese, Korean, and Spanish through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

The Spring 2024 SOC 2 report includes a total of 177 services in scope. For up-to-date information, including when additional services are added, visit the AWS Services in Scope by Compliance Program webpage and choose SOC.

AWS strives to continuously bring services into scope of its compliance programs to help you meet your architectural and regulatory needs. Please reach out to your AWS account team if you have questions or feedback about SOC compliance.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.


Japanese version

第1四半期 2024 SOC 2 レポートの日本語、韓国語、スペイン語版の提供を開始

当社はお客様、規制当局、利害関係者の声に継続的に耳を傾け、Amazon Web Services (AWS) における監査、保証、認定、認証プログラムに関するそれぞれのニーズを理解するよう努めています。この度、AWS System and Organization Controls (SOC) 2 レポートが、日本語、韓国語、スペイン語で利用可能になりました。この翻訳版のレポートは、日本、韓国、ラテンアメリカ、スペインのお客様および規制要件との連携と協力体制を強化するためのものです。

本レポートの日本語、韓国語、スペイン語版には監査人による独立した第三者の意見は含まれていませんが、英語版には含まれています。利害関係者は、日本語、韓国語、スペイン語版の補足として英語版を参照する必要があります。

今後、四半期ごとの以下のレポートで翻訳版が提供されます。SOC 1 統制は、第1四半期 および 第3四半期 SOC 2 レポートに含まれるため、英語版と合わせ、1 年間のレポートの翻訳版すべてがこのスケジュールで網羅されることになります。

  • 第1四半期 SOC 2 (4 月 1 日〜3 月 31 日)
  • 第2四半期 SOC 1 (7 月 1 日〜6 月 30 日)
  • 第3四半期 SOC 2 (10 月 1 日〜9 月 30 日)
  • 第4四半期 SOC 1 (1 月 1 日〜12 月 31 日)

第1四半期 2024 SOC 2 レポートの日本語、韓国語、スペイン語版は AWS Artifact (AWS のコンプライアンスレポートをオンデマンドで入手するためのセルフサービスポータル) を使用してダウンロードできます。AWS マネジメントコンソール内の AWS Artifact にサインインするか、AWS Artifact の開始方法ページで詳細をご覧ください。

第1四半期 2024 SOC 2 レポートの対象範囲には合計 177 のサービスが含まれます。その他のサービスが追加される時期など、最新の情報については、コンプライアンスプログラムによる対象範囲内の AWS のサービスで [SOC] を選択してご覧いただけます。

AWS では、アーキテクチャおよび規制に関するお客様のニーズを支援するため、コンプライアンスプログラムの対象範囲に継続的にサービスを追加するよう努めています。SOC コンプライアンスに関するご質問やご意見については、担当の AWS アカウントチームまでお問い合わせください。

コンプライアンスおよびセキュリティプログラムに関する詳細については、AWS コンプライアンスプログラムをご覧ください。当社ではお客様のご意見・ご質問を重視しています。お問い合わせページより AWS コンプライアンスチームにお問い合わせください。


Korean version

2024년 춘계 SOC 2 보고서의 한국어, 일본어, 스페인어 번역본 제공

Amazon은 고객, 규제 기관 및 이해 관계자의 의견을 지속적으로 경청하여 Amazon Web Services (AWS)의 감사, 보증, 인증 및 증명 프로그램과 관련된 요구 사항을 파악하고 있습니다. AWS System and Organization Controls(SOC) 2 보고서가 이제 한국어, 일본어, 스페인어로 제공됨을 알려 드립니다. 이 번역된 보고서는 일본, 한국, 중남미, 스페인의 고객 및 규제 요건을 준수하고 참여도를 높이는 데 도움이 될 것입니다.

보고서의 일본어, 한국어, 스페인어 버전에는 감사인의 독립적인 의견이 포함되어 있지 않지만, 영어 버전에서는 해당 정보를 확인할 수 있습니다. 이해관계자는 일본어, 한국어 또는 스페인어 버전을 보완하기 위해 영어 버전을 사용해야 합니다.

앞으로 분기마다 다음 보고서가 번역본으로 제공됩니다. SOC 1 통제 조치는 춘계 및 추계 SOC 2 보고서에 포함되어 있으므로, 이 일정은 영어 버전과 함께 모든 번역된 언어로 연중 내내 제공됩니다.

  • 춘계 SOC 2(4/1~3/31)
  • 하계 SOC 1(7/1~6/30)
  • 추계 SOC 2(10/1~9/30)
  • 동계 SOC 1(1/1~12/31)

고객은 AWS 규정 준수 보고서를 필요할 때 이용할 수 있는 셀프 서비스 포털인 AWS Artifact를 통해 한국어, 일본어, 스페인어로 번역된 2024년 춘계 SOC 2 보고서를 다운로드할 수 있습니다. AWS Management Console의 AWS Artifact에 로그인하거나 Getting Started with AWS Artifact(AWS Artifact 시작하기)에서 자세한 내용을 알아보세요.

2024년 춘계 SOC 2 보고서에는 총 177개의 서비스가 포함됩니다. 추가 서비스가 추가되는 시기 등의 최신 정보는 AWS Services in Scope by Compliance Program(규정 준수 프로그램별 범위 내 AWS 서비스)에서 SOC를 선택하세요.

AWS는 고객이 아키텍처 및 규제 요구 사항을 충족할 수 있도록 지속적으로 서비스를 규정 준수 프로그램의 범위에 포함시키기 위해 노력하고 있습니다. SOC 규정 준수에 대한 질문이나 피드백이 있는 경우 AWS 계정 팀에 문의하시기 바랍니다.

규정 준수 및 보안 프로그램에 대한 자세한 내용은 AWS 규정 준수 프로그램을 참조하세요. 언제나 그렇듯이 AWS는 여러분의 피드백과 질문을 소중히 여깁니다. 문의하기 페이지를 통해 AWS 규정 준수 팀에 문의하시기 바랍니다.


Spanish version

El informe de SOC 2 primavera 2024 se encuentra disponible actualmente en japonés, coreano y español

Seguimos escuchando a nuestros clientes, reguladores y partes interesadas para comprender sus necesidades en relación con los programas de auditoría, garantía, certificación y acreditación en Amazon Web Services (AWS). Nos enorgullece anunciar que el informe de controles de sistema y organización (SOC) 2 de AWS se encuentra disponible en japonés, coreano y español. Estos informes traducidos ayudarán a impulsar un mayor compromiso y alineación con los requisitos normativos y de los clientes en Japón, Corea, Latinoamérica y España.

Estas versiones del informe en japonés, coreano y español no contienen la opinión independiente emitida por los auditores, pero se puede acceder a esta información en la versión en inglés del documento. Las partes interesadas deben usar la versión en inglés como complemento de las versiones en japonés, coreano y español.

De aquí en adelante, los siguientes informes trimestrales estarán traducidos. Dado que los controles SOC 1 se incluyen en los informes de primavera y otoño de SOC 2, esta programación brinda una cobertura anual para todos los idiomas traducidos cuando se la combina con las versiones en inglés.

  • SOC 2 primavera (del 1/4 al 31/3)
  • SOC 1 verano (del 1/7 al 30/6)
  • SOC 2 otoño (del 1/10 al 30/9)
  • SOC 1 invierno (del 1/1 al 31/12)

Los clientes pueden descargar los informes de SOC 2 primavera 2024 traducidos al japonés, coreano y español a través de AWS Artifact, un portal de autoservicio para el acceso bajo demanda a los informes de cumplimiento de AWS. Inicie sesión en AWS Artifact mediante la Consola de administración de AWS u obtenga más información en Introducción a AWS Artifact.

El informe de SOC 2 primavera 2024 incluye un total de 177 servicios que se encuentran dentro del alcance. Para acceder a información actualizada, que incluye novedades sobre cuándo se agregan nuevos servicios, consulte los Servicios de AWS en el ámbito del programa de conformidad y seleccione SOC.

AWS se esfuerza de manera continua por añadir servicios dentro del alcance de sus programas de conformidad para ayudarlo a cumplir con sus necesidades de arquitectura y regulación. Si tiene alguna pregunta o sugerencia sobre la conformidad de los SOC, no dude en comunicarse con su equipo de cuenta de AWS.

Para obtener más información sobre los programas de conformidad y seguridad, consulte los Programas de conformidad de AWS. Como siempre, valoramos sus comentarios y preguntas; de modo que no dude en comunicarse con el equipo de conformidad de AWS a través de la página Contacte con nosotros.

Brownell Combs

Brownell Combs
Brownell is a Compliance Program Manager at AWS, where he leads multiple security and privacy initiatives. Brownell holds a Master’s Degree in Computer Science from the University of Virginia and a Bachelor’s Degree in Computer Science from Centre College. He has over 20 years of experience in information technology risk management and CISSP, CISA, CRISC, and GIAC GCLD certifications.

Rodrigo Fiuza

Rodrigo Fiuza
Rodrigo is a Security Audit Manager at AWS, based in São Paulo. He leads audits, attestations, certifications, and assessments across Latin America, the Caribbean, and Europe. Rodrigo has worked in risk management, security assurance, and technology audits for the past 12 years.

Paul Hong

Paul Hong
Paul is a Compliance Program Manager at AWS. He leads multiple security, compliance, and training initiatives within AWS and has over 10 years of experience in security assurance. Paul is a CISSP, CEH, and CPA, and holds a Masters of Accounting Information Systems and a Bachelors of Business Administration from James Madison University, Virginia.

Hwee Hwang

Hwee Hwang
Hwee is an Audit Specialist at AWS based in Seoul, South Korea. Hwee is responsible for third-party and customer audits, certifications, and assessments in Korea. Hwee previously worked in security governance, risk, and compliance and is laser focused on building customers’ trust and providing them assurance in the cloud.

Tushar Jain

Tushar Jain
Tushar is a Compliance Program Manager at AWS, where he leads multiple security, compliance, and training initiatives. He holds a Master of Business Administration from Indian Institute of Management, Shillong, India and a Bachelor of Technology in Electronics and Telecommunication Engineering from Marathwada University, India. He has over 12 years of experience in information security and holds CCSK and CSXF certifications.

Eun Jin Kim

Eun Jin Kim
Eun Jin is a security assurance professional working as the Audit Program Manager at AWS. She mainly leads compliance programs in South Korea for the financial sector. She has more than 25 years of experience and holds a Master’s Degree in Management Information Systems from Carnegie Mellon University in Pittsburgh, Pennsylvania and a Master’s Degree in Law from George Mason University in Arlington, Virginia.

Michael Murphy

Michael Murphy
Michael is a Compliance Program Manager at AWS, where he leads multiple security and privacy initiatives. Michael has 12 years of experience in information security. He holds a Master’s Degree in Computer Engineering and a Bachelor’s Degree in Computer Engineering from Stevens Institute of Technology. He also holds CISSP, CRISC, CISA, and CISM certifications.

Nathan Samuel

Nathan Samuel
Nathan is a Compliance Program Manager at AWS, where he leads multiple security and privacy initiatives. Nathan has a Bachelor’s of Commerce degree from the University of the Witwatersrand, South Africa. He has 21 years’ experience in security assurance and holds the CISA, CRISC, CGEIT, CISM, CDPSE, and Certified Internal Auditor certifications.

Seul Un Sung

Seul Un Sung
Seul Un is a Security Assurance Audit Program Manager at AWS, where she has been leading South Korea audit programs, including K-ISMS and RSEFT, for the past four years. She has a Bachelor’s of Information Communication and Electronic Engineering degree from Ewha Womans University and has 14 years of experience in IT risk, compliance, governance, and audit, and holds the CISA certification.

Hidetoshi Takeuchi

Hidetoshi Takeuchi
Hidetoshi is a Senior Audit Program Manager at AWS, based in Japan, leading Japan and India security certification and authorization programs. Hidetoshi has led information technology, cyber security, risk management, compliance, security assurance, and technology audits for the past 28 years and holds the CISSP certifications.

ryan wilks

Ryan Wilks
Ryan is a Compliance Program Manager at AWS, where he leads multiple security and privacy initiatives. Ryan has 13 years of experience in information security. He has a bachelor of arts degree from Rutgers University and holds ITIL, CISM, and CISA certifications.

Create a customizable cross-company log lake for compliance, Part I: Business Background

Post Syndicated from Colin Carson original https://aws.amazon.com/blogs/big-data/create-a-customizable-cross-company-log-lake-for-compliance-part-i-business-background/

As described in a previous post, AWS Session Manager, a capability of AWS Systems Manager, can be used to manage access to Amazon Elastic Compute Cloud (Amazon EC2) instances by administrators who need elevated permissions for setup, troubleshooting, or emergency changes. While working for a large global organization with thousands of accounts, we were asked to answer a specific business question: “What did employees with privileged access do in Session Manager?”

This question had an initial answer: use logging and auditing capabilities of Session Manager and integration with other AWS services, including recording connections (StartSession API calls) with AWS CloudTrail, and recording commands (keystrokes) by streaming session data to Amazon CloudWatch Logs.

This was helpful, but only the beginning. We had more requirements and questions:

  • After session activity is logged to CloudWatch Logs, then what?
  • How can we provide useful data structures that minimize work to read out, delivering faster performance, using more data, with more convenience?
  • How do we support a variety of usage patterns, such as ongoing system-to-system bulk transfer, or an ad-hoc query by a human for a single session?
  • How should we share and implement governance?
  • Thinking bigger, what about the same question for a different service or across more than one use case? How do we add what other API activity happened before or after a connection—in other words, context?

We needed more comprehensive functionality, more customization, and more control than a single service or feature could offer. Our journey began where previous customer stories about using Session Manager for privileged access (similar to our situation), least privilege, and guardrails ended. We had to create something new that combined existing approaches and ideas:

  • Low-level primitives such as Amazon Simple Storage Service (Amazon S3).
  • Latest features and approaches of AWS, such as vertical and horizontal scaling in AWS Glue.
  • Our experience working with legal, audit, and compliance in large enterprise environments.
  • Customer feedback.

In this post, we introduce Log Lake, a do-it-yourself data lake based on logs from CloudWatch and AWS CloudTrail. We share our story in three parts:

  • Part 1: Business background – We share why we created Log Lake and AWS alternatives that might be faster or easier for you.
  • Part 2: Build – We describe the architecture and how to set it up using AWS CloudFormation templates.
  • Part 3: Add – We show you how to add invocation logs, model input, and model output from Amazon Bedrock to Log Lake.

Do you really want to do it yourself?

Before you build your own log lake, consider the latest, highest-level options already available in AWS–they can save you a lot of work. Whenever possible, choose AWS services and approaches that abstract away undifferentiated heavy lifting to AWS so you can spend time on adding new business value instead of managing overhead. Know the use cases services were designed for, so you have a sense of what they already can do today and where they’re going tomorrow.

If that doesn’t work, and you don’t see an option that delivers the customer experience you want, then you can mix and match primitives in AWS for more flexibility and freedom, as we did for Log Lake.

Session Manager activity logging

As we mentioned in our introduction, you can save logging data to AmazonS3, add a table on top, and query that table using Amazon Athena—this is what we recommend you consider first because it’s straightforward.

This would result in files with the sessionid in the name. If you want, you can process these files into a calendarday, sessionid, sessiondata format using an S3 event notification that invokes a function (and make sure to save it to a different bucket, in a different table, to avoid causing recursive loops). The function could derive the calendarday and sessionid from the S3 key metadata, and sessiondata would be the entire file contents.

Alternatively, you can sign to one log group in CloudWatch logs, have an Amazon Data Firehose subscription filter move that to S3 (this file would have additional metadata in the JSON content and more customization potential from filters). This was used in our situation, but it wasn’t enough by itself.

AWS CloudTrail Lake

CloudTrail Lake is for running queries on events over years of history and with near real-time latency and offers a deeper and more customizable view of events than CloudTrail Event history. CloudTrail Lake enables you to federate an event data store, which lets you view the metadata in the AWS Glue catalog and run Athena queries. For needs involving one organization and ongoing ingesting from a trail (or point-in-time import from Amazon S3, or both), you can consider CloudTrail Lake.

We considered CloudTrail Lake, as either a managed lake option or source for CloudTrail only, but ended up creating our own AWS Glue job instead. This was because of a combination of reasons, including full control over schema and jobs, ability to ingest data from an S3 bucket of our choosing as an ongoing source, fine-grained filtering on account, AWS Region, and eventName (eventName filtering wasn’t supported for management events ), and cost.

The cost of CloudTrail lake based on uncompressed data ingested (data size can be 10 times larger than in Amazon S3) was a factor for our use case. In one test, we found CloudTrail Lake to be 38 times faster to process the same workload as Log Lake, but Log Lake was 10–100 times less costly depending on filters, timing, and account activity. Our test workload was 15.9 GB file size in S3, 199 million events, and 400 thousand files, spread across over 150 accounts and 3 Regions. Filters Log Lake applied were eventname='StartSession', 'AssumeRole', 'AssumeRoleWithSAML', and five arbitrary allow listed accounts. These tests might be different from your use case, so you should do your own testing, gather your own data, and decide for yourself.

Other services

The products mentioned previously are the most relevant to the outcomes we were trying to accomplish, but you should consider security, identity, and compliance products on AWS, too. These products and features can be used either as an alternative to Log Lake or to add functionality.

As an example, Amazon Bedrock can add functionality in three ways:

  • To skip the search and query Log Lake for you
  • To summarize across logs
  • As a source for logs (similar to Session Manager as a source for CloudWatch logs)

Querying means you can have an AI agent query your AWS Glue catalog (such as the Log Lake catalog) for data-based results. Summarizing means you can use generative artificial intelligence (AI) to summarize your text logs from a knowledge base as part of retrieval augmented generation (RAG), to ask questions like “How many log files are exactly the same? Who changed IAM roles last night?” Considerations and limitations apply.

Adding Amazon Bedrock as a source means using invocation logging to collect requests and responses.

Because we wanted to store very large amounts of data frugally (compressed and columnar format, not text) and produce non-generative (data-based) results that can be used for legal compliance and security, we didn’t use Amazon Bedrock in Log Lake—but we will revisit this topic in Part 3 when we detail how to use the approach we used for Session Manager for Amazon Bedrock.

Business background

When we began talking with our business partners, sponsors, and other stakeholders, important questions, problems, opportunities, and requirements emerged.

Why we needed to do this

Legal, security, identity, and compliance authorities of the large enterprise we were working for had created a customer-specific control. To comply with the control objective, use of elevated privileges required a manager to manually review all available data (including any session manager activity) to confirm or deny if use of elevated privileges was justified. This was a compliance use case that, when solved, could be applied to more use cases such as auditing and reporting.

Note on terms:

  • Here, the customer in customer-specific control means a control that is solely the responsibility of a customer, not AWS, as described in the AWS Shared Responsibility Model.
  • In this article, we define auditing broadly as testing information technology (IT) controls to mitigate risk, by anyone, at any cadence (ongoing as part of day-to-day operations, or one time only). We don’t refer to auditing that is financial, only conducted by an independent third-party, or only at certain times. We use self-review and auditing interchangeably.
  • We also define reporting broadly as presenting data for a specific purpose in a specific format to evaluate business performance and facilitate data-driven decisions—such as answering “how many employees had sessions last week?”

The use case

Our first and most important use case was a manager who needed to review activity, such as from an after-hours on-call page the previous night. If the manager needed to have additional discussions with their employee or needed additional time to consider activity, they had up to a week (7 calendar days) before they needed to confirm or deny elevated privileges were needed, based on their team’s procedures. A manager needed to review an entire set of events that all share the same session, regardless of known keywords or specific strings, as part of all available data in AWS. This was the workflow:

  1. Employee uses homegrown application and standardized workflow to access Amazon EC2 with elevated privileges using Session Manager.
  2. API activity in CloudTrail and continuous logging to CloudWatch logs.
  3. The problem space – Data somehow gets procured, processed, and provided (this would become Log Lake later).
  4. Another homegrown system (different from step 1) presents session activity to managers and applies access controls (a manager should only review activity for their own employees, and not be able to peruse data outside their team). This data might be only one StartSession API call and no session details, or might be thousands of lines from cat file
  5. The manager reviews all available activity, makes an informed decision, and confirms or denies if use was justified.

This was an ongoing day-to-day operation, with a narrow scope. First, this meant only data available in AWS; if something couldn’t be captured by AWS, it was out of scope. If something was possible, it should be made available. Second, this meant only certain workflows; using Session Manager with elevated privileges for a specific, documented standard operating procedure.

Avoiding review

The simplest solution would be to block sessions on Amazon EC2 with elevated privileges, and fully automate build and deployment. This was possible for some but not all workloads, because some workloads required initial setup, troubleshooting, or emergency changes of Marketplace AMIs.

Is accurate logging and auditing possible?

We won’t extensively detail ways to bypass controls here, but there are important limitations and considerations we had to consider, and we recommend you do too.

First, logging isn’t available for sessionType Port, which includes SSH. This could be mitigated by ensuring employees can only use a custom application layer to start sessions without SSH. Blocking direct SSH access to EC2 instances using security group policies is another option.

Second, there are many ways to intentionally or accidentally hide or obfuscate activity in a session, making review of a specific command difficult or impossible. This was acceptable for our use case for multiple reasons:

  • A manager would always know if a session started and needed review from CloudTrail (our source signal). We joined to CloudWatch to meet our all available data requirement.
  • Continuous streaming to CloudWatch logs would log activity as it happened. Additionally, streaming to CloudWatch Logs supported interactive shell access, and our use case only used interactive shell access (sessionType Standard_Stream). Streaming isn’t supported for sessionType, InteractiveCommands, or NonInteractiveCommands.
  • The most important workflow to review involved an engineered application with one standard operating procedure (less variety than all the ways Session Manager could be used).
  • Most importantly, the manager was responsible for reviewing the reports and expected to apply their own judgement and interpret what happened. For example, a manager review could result in a follow up conversation with the employee that could improve business processes. A manager might ask their employee, “Can you help me understand why you ran this command? Do we need to update our runbook or automate something in deployment?”

To protect data against tampering, changes, or deletion, AWS provides tools and features such as AWS Identity and Access Management (IAM) policies and permissions and Amazon S3 Object Lock.

Security and compliance are a shared responsibility between AWS and the customer, and customers need to decide what AWS services and features to use for their use case. We recommend customers consider a comprehensive approach that considers overall system design and includes multiple layers of security controls (defense in depth). For more information, see the Security pillar of the AWS Well-Architected Framework.

Avoiding automation

Manual review can be a painful process, but we couldn’t automate review for two reasons: Legal requirements and to add friction to the feedback loop felt by a manager whenever an employee used elevated privileges, to discourage using elevated privileges.

Works with existing

We had to work with existing architecture, spanning thousands of accounts and multiple AWS Organizations. This meant sourcing data from buckets as an edge and point of ingress. Specifically, CloudTrail data was managed and consolidated outside of CloudTrail, across organizations and trails, into S3 buckets. CloudWatch data was also consolidated to S3 buckets, from Session Manager to CloudWatch Logs, with Amazon Data Firehose subscription filters on CloudWatch Logs pointing to S3. To avoid negative side effects on existing business processes, our business partners didn’t want to change settings in CloudTrail, CloudWatch, and Firehose. This meant Log Lake needed features and flexibility that enabled changes without impacting other workstreams using the same sources.

Event filtering is not a data lake

Before we were asked to help, there were attempts to do event filtering. One attempt tried to monitor session activity using Amazon EventBridge. This was limited to AWS API operations recorded by CloudTrail such as StartSession and didn’t include the information from inside the session, which was in CloudWatch Logs. Another attempt tried event filtering CloudWatch in the form of a subscription filter. Also, an attempt was made using EventBridge Event Bus with EventBridge rules, and storage in Amazon DynamoDB. These attempts didn’t deliver the expected results because of a combination of factors:

Size

Couldn’t accept large session log payloads because of the EventBridge PutEvents limit of 256 KB entry size. Saving large entries to Amazon S3 and using the object URL in the PutEvents entry would avoid this limitation in EventBridge, but wouldn’t pass the most important information the manager needed to review (the event’s sessionData element). This meant managing files and physical dependencies, and losing the metastore benefit of working with data as logical sets and objects.

Storage

Event filtering was a way to process data, not storage or a source of truth. We asked, how do we restore data lost in flight or destroyed after landing? If components are deleted or undergoing maintenance, can we still procure, process, and provide data—at all three layers independently? Without storage, no.

Data quality

No source of truth meant data quality checks weren’t possible.  We couldn’t answer questions like: “Did the last job process more than 90 percent of events from CloudTrail in DynamoDB?” or“What percentage are we missing from source to target?”

Anti-patterns

DynamoDB as long-term storage wasn’t the most appropriate data store for large analytical workloads, low I/O, and highly complex many-to-many joins.

Reading out

Deliveries were fast, but work (and time and cost) was needed after delivery. In other words, queries had to do extra work to transform raw data into the needed format at time of read, which had a significant, cumulative effect on performance and cost. Imagine users running a select * from table without any filters on years of data and paying for storage and compute of those queries.

Cost of ownership

Filtering by event contents (sessionData from CloudWatch) required knowledge of session behavior, which was business logic. This meant changes to business logic required changes to event filtering. Imagine being asked to change CloudWatch filters or EventBridge rules based on a business process change, and trying to remember where to make the change, or troubleshoot why expected events weren’t being passed. This meant a higher cost of ownership and slower cycle times at best, and inability to meet SLA and scale at worst.

Accidental coupling

Creates accidental coupling between downstream consumers and low-level events. Consumers who directly integrate against events might get different schemas at different times for the same events, or events they don’t need. There’s no way to manage data at a higher level than event, at the level of sets (like all events for one sessionid), or at the object level (a table designed for dependencies). In other words, there was no metastore layer that separated the schema from the files, like in a data lake.

More sources (data to load in)

There were other, less important use cases that we wanted to expand to later: inventory management and security.

For inventory management, such as identifying EC2 instances running a Systems Manager agent that’s missing a patch, finding IAM users with inline policies, or finding Redshift clusters with nodes that aren’t RA3. This data would come from AWS Config unless it isn’t a supported resource type. We cut inventory management from scope because AWS Config data could be added to an AWS Glue catalog later, and queried from Athena using an approach like the one described in How to query your AWS resource configuration states using AWS Config and Amazon Athena.

For security, Splunk and OpenSearch were already in use for serviceability and operational analysis, sourcing files from Amazon S3. Log Lake is a complementary approach sourcing from the same data, which adds metadata and simplified data structures at the cost of latency. For more information about having different tools analyze the same data, see Solving big data problems on AWS.

More use cases (reasons to read out)

We knew from the first meeting that this was a bigger opportunity than just building a dataset for sessions from Systems Manager for manual manager review. Once we had procured logs from CloudTrail and CloudWatch, set up Glue jobs to process logs into convenient tables, and were able to join across these tables, we could change filters and configuration settings to answer questions about additional services and use cases, too. Similar to how we process data for Session Manager, we could expand the filters on Log Lake’s Glue jobs, and add data for Amazon Bedrock model invocation logging. For other use cases, we could use Log Lake as a source for automation (rules-based or ML), deep forensic investigations, or string-match searches (such as IP addresses or user names).

Additional technical considerations

*How did we define session? We would always know if a session started from StartSession event in CloudTrail API activity. Regarding when a session ended, we did not use TerminateSession because this was not always present and we considered this domain-specific logic. Log Lake enabled downstream customers to decide how to interpret the data. For example, our most important workflow had a Systems Manager timeout of 15 minutes, and our SLA was 90 minutes. This meant managers knew a session with a start time more than 2 hours prior to the current time was already ended.

*CloudWatch data required additional processing compared to CloudTrail, because CloudWatch logs from Firehose were saved in gzip format without gz suffix and had multiple JSON documents in the same line that needed to be processed to be on separate lines. Firehose can transform and convert records, such as invoking a Lambda function to transform, convert JSON to ORC, and decompress data, but our business partners didn’t want to change existing settings.

How to get the data (a deep dive)

To support the dataset needed for a manager to review, we needed to identify API-specific metadata (time, event source, and event name), and then join it to session data. CloudTrail was necessary because it was the most authoritative source for AWS API activity, specifically StartSession and AssumeRole and AssumeRoleWithSAML events, and contained context that didn’t exist in CloudWatch Logs (such as the error code AccessDenied) which could be useful for compliance and investigation. CloudWatch was necessary because it contained the keystrokes in a session, in the CloudWatch log’s sessionData element. We needed to obtain the AWS source of record from CloudTrail, but we recommend you check with your authorities to confirm you really need to join to CloudTrail. We mention this in case you hear this question “why not derive some sort of earliest eventTime from CloudWatch logs, and skip joining to CloudTrail entirely? That would cut size and complexity by half.”

To join CloudTrail (eventTime, eventname, errorCode, errorMessage, and so on) with CloudWatch (sessionData), we had to do the following:

  1. Get the higher level API data from CloudTrail (time, event source, and event name), as the authoritative source for auditing Session Manager. To get this, we needed to look inside all CloudTrail logs and get only the rows with eventname=‘StartSession’ and eventsource=‘ssm.amazonaws.com’ (events from Systems Manager)—our business partners described this as looking for a needle in a haystack, because this could be only one session event across millions or billions of files. After we obtained this metadata, we needed to extract the sessionid to know what session to join it to, and we chose to extract sessionid from responseelements. Alternatively, we could use useridentity.sessioncontext.sourceidentity if a principal provided it while assuming a role (requires sts:SetSourceIdentity in the role trust policy).

Sample of a single record’s responseelements.sessionid value: "sessionid":"theuser-thefederation-0b7c1cc185ccf51a9"

The actual sessionid was the final element of the logstream: 0b7c1cc185ccf51a9.

  1. Next we needed to get all logs for a single session from CloudWatch. Similarly to CloudTrail, we needed to look inside all CloudWatch logs landing in Amazon S3 from Firehose to identify only the needles that contained "logGroup":"/aws/ssm/sessionlogs". Then, we could get sessionid from logstream or sessionId, and get session activity from the message.sessionData.

Sample of a single record’s logStream element: "sessionId": "theuser-thefederation-0b7c1cc185ccf51a9"

Note: Looking inside the log isn’t always necessary. We did it because we had to work with existing logs Firehose put to Amazon S3, which didn’t have the logstream (and sessionid) in the file name. For example, a file from Firehose might have a name like

cloudwatch-logs-otherlogs-3-2024-03-03-22-22-55-55239a3d-622e-40c0-9615-ad4f5d4381fa

If we were able to use the ability of Session Manager to send to S3 directly, the file name in S3 is the loggroup (theuser-thefederation-0b7c1cc185ccf51a9.dms)and could be used to derive sessionid without looking inside the file.

  1. Downstream of Log Lake, consumers could join on sessionid which was derived in the previous step.

What’s different about Log Lake

If you remember one thing about Log Lake, remember this: Log Lake is a data lake for compliance-related use cases, uses CloudTrail and CloudWatch as data sources, has separate tables for writing (original raw) and reading (read-optimized or readready), and gives you control over all components so you can customize it for yourself.

Here are some of the signature qualities of Log Lake:

Legal, identity, or compliance use cases

This includes deep dive forensic investigation, meaning use cases that are large volume, historical, and analytical. Because Log Lake uses Amazon S3, it can meet regulatory requirements that require write-once-read-many (WORM) storage.

AWS Well-Architected Framework

Log Lake applies real-world, time-tested design principles from the AWS Well-Architected Framework. This includes, but is not limited to:

Operational Excellence also meant knowing service quotas, performing workload testing, and defining and documenting runbook processes. If we hadn’t tried to break something to see where the limit is, then we considered it untested and inappropriate for production use. To test, we would determine the highest single day volume we’d seen in the past year, and then run that same volume in an hour to see if (and how) it would break.

High-Performance, Portable Partition Adding (AddAPart)

Log Lake adds partitions to tables using Lambda functions with SQS, a pattern we call AddAPart. This uses Amazon Simple Query Service (SQS) to decouple triggers (files landing in Amazon S3) from actions (associating that file with metastore partition). Think of this as having four F’s:

This means no AWS Glue crawlers, no alter table or msck repair table to add partitions in Athena, and can be reused across sources and buckets. The management of partitions in Log Lake makes using partition-related features available in AWS Glue, including AWS Glue partition indexes and workload partitioning and bounded execution.

File name filtering uses the same central controls for lower cost of ownership, faster changes, troubleshooting from one location, and emergency levers—this means that if you want to avoid log recursion happening from a specific account, or want to exclude a Region because of regulatory compliance, you can do it in one place, managed by your change control process, before you pay for processing in downstream jobs.

If you want to tell a team, “onboard your data source to our log lake, here are the steps you can use to self-serve,” you can use AddAPart to do that. We describe this in Part 2.

Readready Tables

In Log Lake, data structures offer differentiated value to users, and original raw data isn’t directly exposed to downstream users by default. For each source, Log Lake has a corresponding read-optimized readready table.

Instead of this:

from_cloudtrail_raw

from_cloudwatch_raw

Log Lake exposes only these to users:

from_cloudtrail_readready

from_cloudwatch_readready

In Part 2, we describe these tables in detail. Here are our answers to frequently asked questions about readready tables:

Q: Doesn’t this have an up-front cost to process raw into readready? Why not pass the work (and cost) to downstream users?

A: Yes, and for us the cost of processing partitions of raw into readready happened once and was fixed, and was offset by the variable costs of querying, which was from many company-wide callers (systemic and human), with high frequency, and large volume.

Q: How much better are readready tables in terms of performance, cost, and convenience? How do you achieve these gains? How do you measure “convenience”?

A: In most tests, readready tables are 5–10 times faster to query and more than 2 times smaller in Amazon S3. Log Lake applies more than one technique: omitting columns, partition design, AWS Glue partition indexes, data types (readready tables don’t allow any nested complex data types within a column, such as struct<struct>), columnar storage (ORC), and compression (ZLIB). We measure convenience as the amount of operations required to join on a sessionid; using Log Lake’s readready tables this is 0 (zero).

Q: Do raw and readready use the same files or buckets?

A: No, files and buckets are not shared. This decouples writes from reads, improves both write and read performance, and adds resiliency.

This question is important when designing for large sizes and scaling, because a single job or downstream read alone can span millions of files in Amazon S3. S3 scaling doesn’t happen immediately, so queries against raw or original data involving many tiny JSON files can cause S3 503 errors when it exceeds 5,500 GET/HEAD per second. More than one bucket helps avoid resource saturation. There is another option that we didn’t have when we created Log Lake: S3 Express One Zone. For reliability, we still recommend not putting all your files in one bucket. Also, don’t forget to filter your data.

Customization and control

You can customize and control all components (columns or schema, data types, compression, job logic, job schedule, and so on) because Log Lake is built using AWS primitives—such as Amazon SQS and Amazon S3—for the most comprehensive combination of features with the most freedom to customize. If you want to change something, you can.

From mono to many

Rather than one large, monolithic lake that is tightly coupled to other systems, Log Lake is just one node in a larger network of distributed data products across different data domains—this concept is data mesh. Just like the AWS APIs it is built on, Log Lake abstracts away heavy lifting and enables users to move faster, more efficiently, and not wait for centralized teams to make changes. Log Lake does not try to cover all use cases—instead, Log Lake’s data can be accessed and consumed by domain-specific teams, empowering business experts to self-serve.

When you need more flexibility and freedom

As builders, sometimes you want to dissect a customer experience, find problems, and figure out ways to make it better. That means going a layer down to mix and match primitives together to get more comprehensive features and more customization, flexibility, and freedom.

We built Log Lake for our long-term needs, but it would have been easier in the short-term to save Session Manager logs to Amazon S3 and query them with Athena. If you have considered what already exists in AWS, and you’re sure you need more comprehensive abilities or customization, read on to Part 2: Build, which explains Log Lake’s architecture and how you can set it up.

If you have feedback and questions, let us know in the comments section.

References


About the authors

Colin Carson is a Data Engineer at AWS ProServe. He has designed and built data infrastructure for multiple teams at Amazon, including Internal Audit, Risk & Compliance, HR Hiring Science, and Security.

Sean O’Sullivan is a Cloud Infrastructure Architect at AWS ProServe. He has over 8 years industry experience working with customers to drive digital transformation projects, helping architect, automate, and engineer solutions in AWS.

AWS completes the first GDV joint audit with participant insurers in Germany

Post Syndicated from Servet Gözel original https://aws.amazon.com/blogs/security/aws-completes-the-first-gdv-joint-audit-with-participant-insurers-in-germany/

We’re excited to announce that Amazon Web Services (AWS) has completed its first German Insurance Association (GDV) joint audit with GDV participant members, which provides assurance to customers in the German insurance industry for the security of their workloads on AWS. This is an important addition to the joint audits performed at AWS by our regulated customers within the financial services industry. Joint audits are an efficient method to provide additional assurance to a group of customers on the “security of the cloud” (as described in the AWS Shared Responsibility Model), in addition to Compliance Programs (for example, C5) and resources that are provided to customers on AWS Artifact.

At AWS, security is our top priority. As customers embrace the scalability and flexibility of AWS, we’re helping them evolve security and compliance into key business enablers. We’re obsessed with earning and maintaining customer trust, and we provide our financial services customers, their end users, and regulatory bodies with the assurance that AWS has the necessary controls in place to help protect their most sensitive material and regulated workloads.

With the increasing digitalization of the financial services industry, and the importance of cloud computing as a key enabling technology for digitalization, security and governance is becoming an ever-more-significant priority for financial services companies. Our engagement with GDV members is an example of how AWS supports customers’ risk management and regulatory compliance. For the first time, this joint audit meticulously assessed the AWS controls that enable us to help protect customers’ workloads, while adhering to strict regulatory obligations. For insurers, moving their workloads to AWS helps protect customer data, support continuity of business-critical operations, and meet new standards in regulatory reporting.

GDV is the association of private insurers in Germany, representing around 470 members in the industry, and is a key player within the German and European financial services industries. GDV’s members participating in this joint audit have reached out to AWS to exercise their audit rights. For this cycle, the 35 participating members from the German insurance industry decided to appoint the Deutsche Cyber-Sicherheitsorganisation GmbH (DCSO) as the single external audit service provider, to perform the audit on behalf of each of the participating members. Because many participating members are affiliates of larger insurance groups and the audit report can be used throughout the group, a coverage of over 70% of the German market in terms of revenue is achieved.

Audit preparations

The scope of the audit was defined with reference to the Federal Office for Information Security (BSI) C5 Framework. It included key domains such as identity and access management, as well as AWS services such as Amazon Elastic Compute Cloud (Amazon EC2), and Regions relevant to participant members such as the Europe (Frankfurt) Region (eu-central-1).

Audit fieldwork

This audit fieldwork phase started after a kick-off in Berlin, Germany. It used a remote approach, with work occurring through the use of videoconferencing and through a secure audit portal for the inspection of evidence. Auditors assessed AWS policies, procedures, and controls, following a risk-based approach, and using sampled evidence, deep-dive sessions and follow-up questions to clarify provided evidence. In the DCSO’s own words regarding their experience during the audit, “We experienced a transparent and comprehensive audit process and appreciate the professional approach as well as the commitment shown by AWS in addressing all our inquiries.”

Audit results

The audit was carried out and completed according to the assessment criteria that were mutually agreed upon by AWS and auditors on behalf of participating members. After a joint review by the auditors and AWS, the auditors finalized the audit report. The results of the GDV joint audit are only available to the participating members and their regulators. The results provide participating members with assurance regarding the AWS controls environment, helping members remove compliance blockers, accelerate their adoption of AWS services, obtain confidence, and gain trust in AWS security controls.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Servet Gözel

Servet Gözel
Servet is a Principal Audit Program Manager in security assurance at AWS, based in Munich, Germany. Servet leads customer audits and assurance programs across Europe. For the past 19 years, he has worked in IT audit, IT advisory, and information security roles areas across various industries and held the CISO role for a group company under a leading insurance provider in Germany.

Andreas Terwellen

Andreas Terwellen
Andreas is a Senior Manager in security audit assurance at AWS, based in Frankfurt, Germany. His team is responsible for third-party and customer audits, attestations, certifications, and assessments across Europe. Previously, he was a CISO in a DAX-listed telecommunications company in Germany. He also worked for different consulting companies managing large teams and programs across multiple industries and sectors.

Daniele Basriev

Daniele Basriev
Daniele is a Security Audit Program Manager at AWS who manages customer security audits and third-party audit programs across Europe. In the past 19 years, he has worked in a wide array of industries and on numerous control frameworks within complex fast-paced environments. He built his expertise in Big 4 accounting firms and then moved into IT security strategy, IT governance, and compliance roles across multiple industries.