Tag Archives: Technical How-to

Managing identity source transition for AWS IAM Identity Center

Post Syndicated from Xiaoxue Xu original https://aws.amazon.com/blogs/security/managing-identity-source-transition-for-aws-iam-identity-center/

AWS IAM Identity Center manages user access to Amazon Web Services (AWS) resources, including both AWS accounts and applications. You can use IAM Identity Center to create and manage user identities within the Identity Center identity store or to connect seamlessly to other identity sources.

Organizations might change the configuration of their identity source in IAM Identity Center for various reasons. These include switching identity providers (IdPs), expanding their identity footprint, adopting new features, and so on. These transitions can disrupt user access and require planning to minimize downtime.

In this blog post, we walk you through the process of switching from one identity source to another and provide sample code that you can use to assist with the transition.

Background

The identity source configured in IAM Identity Center determines where users and groups are created and managed. Each organization can connect to only one identity source at a time. Identity Center supports three main identity source options:

  1. Identity Center directory: This is the default identity store for IAM Identity Center. You can use it to directly create and administer your users and groups within Identity Center without relying on an external provider.
  2. Active Directory: You can configure integration with an on-premises Active Directory or with AWS Managed Microsoft AD using AWS Directory Service. This integration enables you to use your existing Active Directory identities and group memberships.
  3. External IdP: You can continue using your current third-party IdPs that support SAML 2.0, such as Okta Universal Directory or Microsoft Entra ID (formerly Azure AD).

Understanding these identity source options can help you choose the source that best fits your user management needs based on your existing infrastructure and authentication requirements.

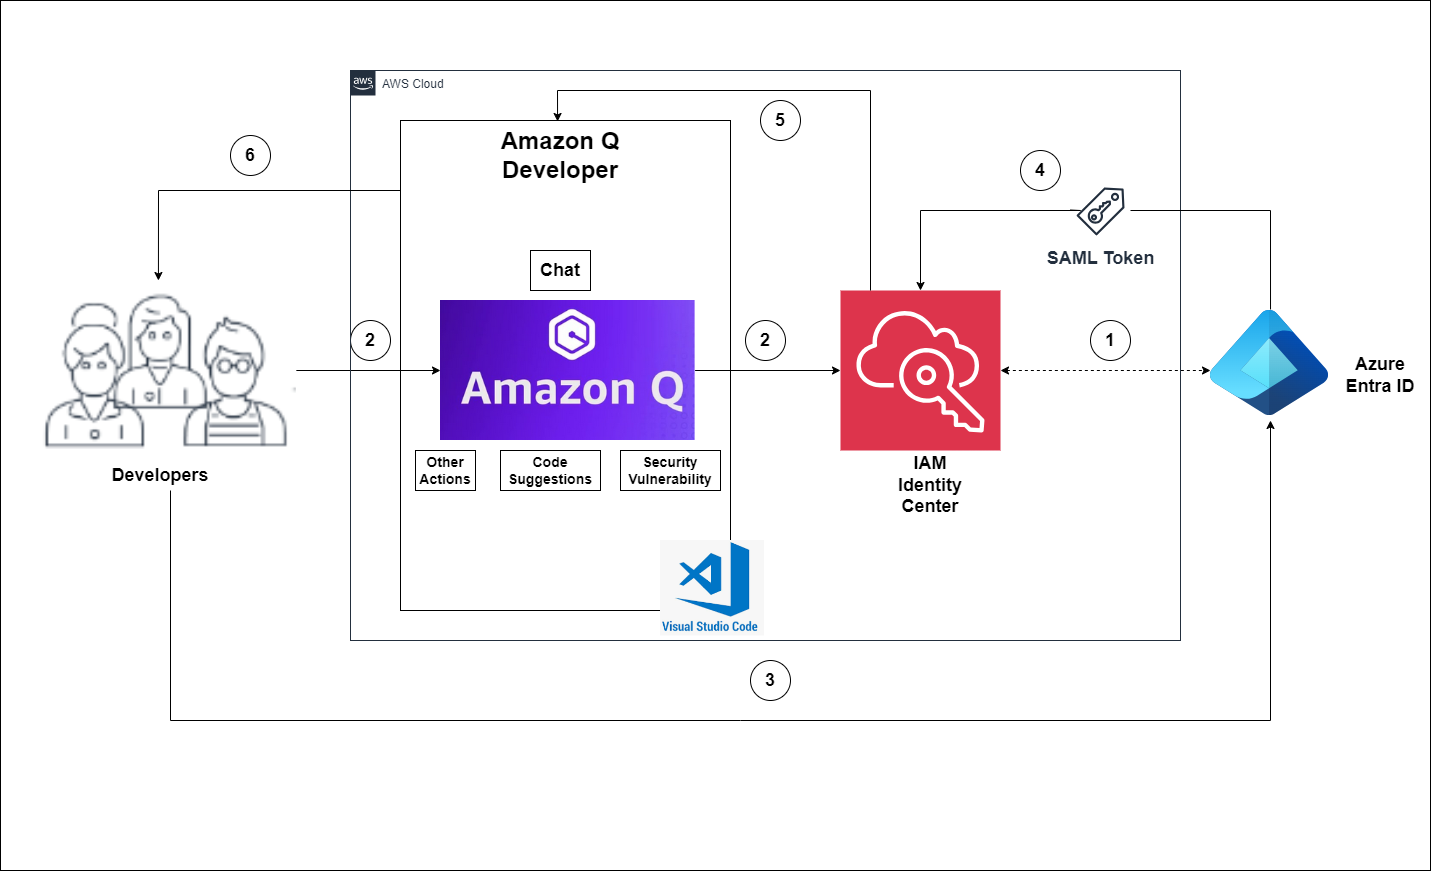
Figure 1 explains the flow of users and groups accessing AWS resources. This access is granted through the following:

Figure 1: Granting access to AWS resources for users and groups managed by an identity source in IAM Identity Center

Figure 1: Granting access to AWS resources for users and groups managed by an identity source in IAM Identity Center

When you change the identity source, the work required varies depending on the original and new sources. AWS documentation details these considerations. In minimal impact scenarios, assignments remain intact, although you need to force password resets or verify correct assertions from the new source. More disruptive scenarios delete users, groups, and their assignments. In those scenarios, you need to restore the deleted entries after changing the identity source.

Sample deployment

This deployment covers permission sets and application assignments’ backup and restore. These scripts associate assignments with unique user attributes such as UserName, and group attributes such as DisplayName. Attributes that might change during the user and group restoration process, such as UserId and GroupId, aren’t used.

What isn’t covered includes users, groups, permission sets, and applications backup and restore.

  • Users and groups backup and restore aren’t covered because they depend heavily on the format of the source and target IdPs.
  • Because we’re working with identity source switching, the permission sets will remain unchanged and applications will not be deleted.
  • If you’re changing IdPs as part of an AWS Region , the IAM Identity Center instance will be deleted. The applications and permission sets will be deleted in addition to assignments. In this case, you must redeploy the applications. See How to automate the review and validation of permissions for users and groups in AWS IAM Identity Center for information about backing up permission sets.

The sample scripts and detailed steps are available on GitHub.

Note: This solution is available in the GitHub aws-samples repository. You can report bugs or make feature requests through GitHub Issues. The builders of this solution can help with GitHub issues. Enterprise Support customers can reach out to their Technical Account Manager (TAM) for further questions or feature requests.

Walkthrough

In this section, we walk you through the process of transitioning to a new identity source in IAM Identity Center.

Step 1: Backup users, groups, and assignments from the current identity source

This step is critical to preserve users’ information and their associated access scope.

How to backup users and groups:

Note: For some external IdPs, there are native integrations with Active Directory, such as Okta AD integration and Ping One AD Connect. You can set up a native integration and sync users and groups data without needing to backup and restore that data.

Assignments can be backed up by running the backup.py file from GitHub. Replace <IDC_STORE_ID> with your Identity Store ID (it looks like d-1234567890), and replace <IDC_ARN> with the Amazon Resource Name (ARN) for your IAM Identity Center instance.

python3 backup.py --idc-id <IDC_STORE_ID> --idc-arn <IDC_ARN>

This script uses both IAM Identity Center APIs and Identity Store APIs as shown in Figure 2 that generates permission set assignments backup files (UserAssignments.json and GroupAssignments.json) and an application assignments backup file (AppAssignments.json).

Figure 2: APIs used for backing up assignments

Figure 2: APIs used for backing up assignments

Step 2: Restore and validate the backed-up users and groups in the target identity source

The target will become the new authoritative identity source. When done, verify that the group memberships and attributes have been correctly transferred.

  • If the target is an IAM Identity Center directory, use APIs such as CreateUser, CreateGroup, and CreateGroupMembership to restore from the previous backup file.
  • If the target is Active Directory or an external IdP, use the corresponding native import features or integration tools to restore.

Step 3: Configure IAM Identity Center to connect to the new identity source and synchronize users and groups

Update your IAM Identity Center configuration to point to the new source. If applicable, use tools such as configurable AD sync or automatic provisioning with SCIM to synchronize your restored identities.

WARNING: While the directory is being rebuilt, your users will not have access to AWS accounts or applications through IAM Identity Center until all assignments are restored in Step 4.

Step 4: Restore assignments to users and groups in the new identity source

The APIs used to restore assignments are as shown in Figure 3.

Figure 3: APIs used for restoring assignments

Figure 3: APIs used for restoring assignments

Assignments can be restored by running the restore.py file from GitHub. Replace <NEW_IDC_STORE_ID> with your newly configured Identity Store ID (it looks like d-1234567890) and replace <IDC_ARN> with the ARN for your IAM Identity Center instance.

python3 restore.py --idc-id <NEW_IDC_STORE_ID> --idc-arn <IDC_ARN>

This script uses the APIs illustrated in Figure 2 and picks up backup files (UserAssignments.json, GroupAssignments.json, and AppAssignments.json) from Step 1 by default. Account permission set assignment results are automatically retrieved five times using exponential backoff. If the result is other than SUCCEEDED after five retries, the principal ID will be marked as failed and exported in error logs.

Note: For AWS managed applications that maintain a separate identity source, using the CreateApplicationAssignments API to restore application assignments will not preserve user access. These applications typically have dependencies on the original identity source ID, or dependencies on UserId and GroupId from the original identity source. This dependency is represented by importing users or groups from IAM Identity Center during the AWS managed application creation process. Example AWS managed applications include Amazon SageMaker Studio and Amazon Q Developer. These applications must be restored on a case-by-case basis and can require redeployment of the application.

Step 5: Validate user access using the new identity source

Make sure that users can still access the expected accounts and applications.

Conclusion

Transitioning your identity source in IAM Identity Center requires careful planning and implementation. This post outlined the steps to manage this transition. By following these steps, you can streamline the transition process, providing a smooth and efficient transfer of user access with minimal downtime. To get started, see the GitHub repository. For related posts, visit the AWS Security Blog channel and search for IAM Identity Center.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Xiaoxue Xu
Xiaoxue Xu

Xiaoxue Xu is a Solutions Architect for AWS based in Toronto. She primarily works with Financial Services customers to help secure their workload and design scalable solutions on the AWS Cloud.
Kanwar Bajwa
Kanwar Bajwa

Kanwar Bajwa is a Principal Technical Account Manager at AWS who works with customers to optimize their use of AWS services and achieve their business objectives.
Yee Fei Ooi
Yee Fei Ooi

Yee Fei is a Solutions Architect supporting independent software vendor (ISV) customers in Singapore and is part of the Containers TFC. She enjoys helping her customers to grow their businesses and build solutions that automate, innovate, and improve efficiency.

Building a three-tier architecture on a budget

Post Syndicated from Adam Nemeth original https://aws.amazon.com/blogs/architecture/building-a-three-tier-architecture-on-a-budget/

AWS customers often look for ways to run their systems within or under budget, avoiding unnecessary costs. This post offers practical advice on designing scalable and cost-efficient three-tier architectures by using serverless technologies within the AWS Free Tier.

With AWS, you can start small and scale cost-effectively as your business demand increases. You can begin with minimal investments by using the Free Tier to build a minimum viable product (MVP). Then you can expand resources as your user base grows and your needs evolve, and transition to a full-fledged, large-scale application.

In this blog post, you will learn how to build a three-tier architecture that predominantly relies on AWS service usage within the Free Tier, resulting in a highly affordable architecture.

Note: The Free Tier offerings mentioned within this blog post are subject to change. Always check the AWS Free Tier page for the most current information.

Background: Understanding the AWS Free Tier

The Free Tier provides users with access to a range of AWS services at no cost within predefined monthly usage limits. This offering helps users to run experimentation, development, and even production workloads without charges. The Free Tier is available for more than 100 AWS products today, including Amazon Simple Storage Service (Amazon S3), Amazon Elastic Compute Cloud (Amazon EC2), and Amazon Relational Database Service (Amazon RDS). Depending on the product, there are three types of Free Tier offers:

  • Free trials – Short-term trial offers that start when the first usage begins. After the trial period expires, you pay standard service rates.
  • 12 months free – Offers available to new AWS customers for 12 months following their sign-up date. After the 12-month free term expires, you pay standard service rates.
  • Always free – Offers available to both existing and new AWS customers indefinitely.

For example, the AWS Lambda Free Tier includes one million free requests per month and 400,000 GB-seconds of compute time per month usable for functions across both x86 and AWS Graviton processors. The AWS Lambda Free Tier falls under the always free category.

Walkthrough: Three-tier architecture on AWS

Cost efficiency is a prominent advantage of using AWS serverless services. These services decrease the need for provisioning and managing servers, reducing operational overhead and labor costs. Serverless services like AWS Lambda and Amazon API Gateway use a pay-as-you-go model. This way, you only pay for the resources you consume, providing significant savings compared to maintaining idle infrastructure. Serverless technologies also feature automatic scaling and built-in high availability to increase agility and optimize costs.

A three-tier architecture is a popular implementation of a multi-tier architecture and consists of a presentation tier, business logic tier, and data tier. A three-tier architecture separates an application’s functionality into distinct layers (presentation, business logic, and data) to enable scalability, modularity, and flexibility in software development. This type of architecture is suitable for building a wide range of applications such as web applications, enterprise systems, and mobile apps.

The following image is an example of a three-tier architecture fully built with AWS serverless services. In this example, users authenticate and navigate to the website in the presentation tier. They call APIs, which invoke Lambda functions at the business logic tier. Data is stored in DynamoDB at the data tier.

Users authenticate through Amazon Cognito and navigate to the website in the presentation tier. They call APIs, which invoke Lambda functions at the business logic tier. Data is stored in DynamoDB at the data tier.

Figure 1: Example of a three-tier architecture on AWS

In the following sections, we explore how to use AWS serverless services within the Free Tier to build a similar architecture.

Note: The Free Tier offerings mentioned within this blog post are subject to change. Always check the AWS Free Tier page for the most current information.

Presentation tier

The presentation tier is where your users interact with your offering, such as a webpage or an app. You can use the following services within the Free Tier to build your presentation tier.

AWS service How you can use it Free Tier details*
Amazon S3 Host static and dynamic assets, like a React Single Page Application (SPA), and distribute them to your end users. For the first year, you get 5 GB of standard storage, 20,000 GET requests and 2,000 PUT requests. See Amazon S3 pricing for details.
Amazon CloudFront Use with Amazon S3 for a faster and more performant distribution of your assets to end users. CloudFront gives you access to the AWS content delivery network with more than 410 points of presence worldwide. CloudFront includes an Always Free Tier, with 1 TB of data transfer out to the internet per month and 10 million HTTP(S) requests per month. See Amazon CloudFront pricing for details.
Amazon Cognito Use Amazon Cognito user pools to authenticate your users. You can also integrate Amazon Cognito within your application’s UI for a seamless login experience. Amazon Cognito has an Always Free Tier, including up to 50,000 monthly active users. It also includes 10 GBs of cloud sync storage and 1 million sync operations per month, valid for the first 12 months after sign-up. See Amazon Cognito pricing for details.

*as of September 2024

Business logic tier

The business logic tier is where code translates user actions to application functionality. You can use the following services within the Free Tier to build your business logic tier.

AWS service How you can use it Free Tier details*
Amazon API Gateway Build a front door to your application’s backend by creating REST or WebSocket APIs. Get 1 million monthly API calls for free, valid for the first 12 months after sign-up. See Amazon API Gateway pricing for details.
AWS Lambda Use AWS Lambda for a serverless compute environment that integrates with API Gateway. You can embed your business logic into functions that run on AWS without the need for you to run and manage infrastructure. The Always Free Tier offers 1 million free requests and 400,000 GB-seconds of compute time per month. See AWS Lambda pricing for details.

*as of September 2024

Data tier

The data tier is where your data is stored. You can use the following service within the Free Tier to build your data tier.

AWS service How you can use it Free Tier details*
Amazon DynamoDB Use this serverless NoSQL database for storing data and tracking transactions. In the context of a three-tier architecture, DynamoDB stores and manages the application’s data, providing reliable and secure data access to the business logic tier. The Always Free Tier offers 25GB of free storage, with up to 200 million requests, 25 write capacity units (WCUs), and 25 read capacity units (RCUs) per month.

*as of September 2024

Walkthrough: Monitoring your usage to avoid unexpected charges

If you use consolidated billing or AWS Organizations, the Free Tier usage accumulates at the management account level. Each management account receives one quota of the Free Tier.

To monitor your Free Tier usage and avoid unexpected charges, you can use the following resources:

The following image shows an example of the Free Tier page in the AWS Billing and Cost Management console.

Free Tier dashboard showing usage limit, current usage, and forecasted usage for in-scope services.

Figure 2: AWS Free Tier view in the Cost and Usage Report

We also recommend configuring a zero spend budget within the AWS Billing and Cost Management console. With this budget, you receive notifications when your usage exceeds the Free Tier limits, helping you to avoid unexpected charges. The following image shows an example of this budget setup.

Choose budget type menu with Use a template and Zero spend budget both selected.

Figure 3: Zero spend budget

Conclusion

In this post, we explored how to use AWS serverless services within the Free Tier to build a three-tier application. We also explored how to monitor your Free Tier usage. The Free Tier offers a chance to experiment and develop without additional costs, helping businesses minimize infrastructure expenses early on. AWS serverless architectures bring benefits like cost savings, flexibility, and scalability.

Beyond using services within the Free Tier, you can further optimize the cost of your AWS serverless application. For instance, to prevent incurring unnecessary inter-Region data transfer costs, we recommend starting with a single Region deployment for your application.

To learn more about the Free Tier and which services it offers, check out the AWS Free Tier FAQs.

Additionally, you can explore various architectural patterns for AWS serverless multi-tier architectures and the Serverless Full Stack WebApp Starter Kit to create scalable and cost-effective solutions on AWS.

Amazon ECS Multi-region Deployment with Amazon CodeCatalyst

Post Syndicated from Piyush Mattoo original https://aws.amazon.com/blogs/devops/amazon-ecs-multi-region-deployment-with-amazon-codecatalyst/

Many AWS customers run their mission-critical workloads across multiple AWS regions to serve geographically dispersed customer base, meet disaster recovery objectives or address local laws and regulations. Amazon CodeCatalyst is a unified software development service designed to streamline and accelerate the process of building and delivering applications on AWS. It is an all-in-one platform for managing your entire development lifecycle, from planning and collaboration to continuous integration, deployment, and scaling. Amazon CodeCatalyst aims to boost developer productivity, ensure consistency, and improve the overall software development experience on AWS. By leveraging Amazon CodeCatalyst for multi-region deployments, AWS customers can ensure high availability and disaster recovery and comply with various regulatory requirements, all while improving their development and deployment process.

In this post, we will walk you through a solution which allows you to easily control updates to applications that are deployed across multiple AWS regions using Amazon CodeCatalyst.

Architecture

In this post, we are going to consider a containerized application running on Amazon Elastic Container Service (Amazon ECS) deployed in two different regions us-east-1 and us-west-2. We will walk you through how to configure an Amazon CodeCatalyst workflow to perform the deployment in stages, limiting the deployment scope to one region at a time (Figure 1).

This diagram shows an Amazon CodeCatalyst workflow the begins with the user pushing code to a repository and the workflow deploy to Amazon ECS region 1 then to Amazon ECS region 2
Figure 1: Amazon ECS Multi Region deployment

Here are the high-level steps in the multi-region deployment process.

  1. The developer makes updates to the application code base and pushes the code changes to the source repository hosted in Amazon CodeCatalyst
  2. This code push invokes an Amazon CodeCatalyst workflow for the multi-region deployment. In this example, the workflow deploys changes to containerized application running on Amazon ECS in two regions.
  3. The deployment to different regions happens in stages. In Step 3, the updates get deployed to region 1. This staged approach allows for initial testing and validation in one AWS region before proceeding.
  4. Once the deployment (and any associated validation steps) is completed successfully in region 1, the workflow proceeds with deployment to the second AWS region.

Limiting the scope of each individual deployment limits the potential impact on customers from failed production deployments and prevents a multi-region impact.

Prerequisites

  • You need access to an AWS account. If you don’t have one, you can create a new AWS account.
  • Follow Amazon ECS Multi-Region Workshop to deploy a simple containerized application across two different AWS regions. Clone the repository and then follow steps to deploy the foundation, data and backend stack. Note the outputs from workshop-backend-main & workshop-backend-secondary, we’ll use them later on in this post.
  • Follow the Amazon ECR user guide to create an Amazon Elastic Container Registry (Amazon ECR) repository named codecatalyst-ecs-image-repo.
  • Create an Amazon CodeCatalyst space, with an empty Amazon CodeCatalyst project named codecatalyst-ecs-project and an Amazon CodeCatalyst environment called codecatalyst-ecs-environment. Associate your AWS account to the CodeCatalyst space. Follow the Amazon CodeCatalyst tutorial to set these up.
  • An AWS Identity and Access Management (IAM) role in the Amazon CodeCatalyst space to provide Amazon CodeCatalyst service permissions to build and deploy applications. Note the name of this role as you’ll use it later in this post.
  • Create an Amazon CodeCatalyst source repository titled ecs-multi-region-repo following the instructions in the documentation.
  • Local installation of Visual Studio Code & Remote Development extension pack.

Walkthrough

Step 1: Create an Amazon CodeCatalyst Dev Environment

In this step, you will create an Amazon CodeCatalyst Dev Environment directly linked to your source repository ecs-multi-region-repo allowing you to work on your Amazon ECS Multi Region application code and configuration files.

  • Open Amazon CodeCatalyst and navigate to your project
  • In the left navigation pane, choose Code and then choose Source repositories
  • Choose the source repository ecs-multi-region-repo for the Amazon ECS multi-region application
  • Choose Create Dev Environment
  • Choose Visual Studio Code  from the drop-down menu
  • In Create Dev Environment and open with Visual Studio Code page (Figure 2), choose Create to create a Visual Studio Code development environment

Create Dev Environment in Amazon CodeCatalyst

Figure 2: Create Dev Environment in Amazon CodeCatalyst

  • Choose Open in Visual Studio Code when prompted (Figure 3), this establishes a remote connection to Dev Environment from your local Visual Studio Code. Keep this window open as you will need it for Step 2

Open Dev Environment with Visual Studio Code 

Figure 3: Open Dev Environment with Visual Studio Code

Step 2: Add Source files to Amazon CodeCatalyst source repository

In this step you will add the necessary source files source files to the Amazon CodeCatalyst repository you created in the pre-requisites, including the sample Amazon ECS multi-region application and the Amazon ECS task definition file.

  • Inside the Visual Studio Code IDE, choose Terminal in the top menu.
  • Select New Terminal or use an existing terminal window if you prefer.
  • Clone the Github project inside your project folder by running the below commands in the terminal.
    git clone https://github.com/aws-samples/amazon-ecs-multi-region.git
    rm -rf amazon-ecs-multi-region/.git
    cp -r amazon-ecs-multi-region/ ecs-multi-region-repo
    cd ecs-multi-region-repo/

  • You need to create an Amazon ECS task definition file for the sample application. Create a file named task.json inside the app folder. Paste the below contents into the task.json replacing placeholder <Account_ID> with your AWS Account ID and <ecsTaskExecutionRole> with your role from workshop-backend-main outputs.
    {
    "executionRoleArn":"arn:aws:iam:<Account_ID>:role/<ecsTaskExecutionRole>",
    "containerDefinitions": [
    {
    "name": "web",
    "image": "$REPOSITORY_URI:$IMAGE_TAG",
    "essential": true,
    "portMappings": [
    {
    "hostPort": 5000,
    "protocol": "tcp",
    "containerPort": 5000
    }
    ],
    "environment": [
    {
    "name": "DYNAMODB_TABLE_NAME",
    "value": "workshop-table"
    }
    ]
    }
    ],
    "requiresCompatibilities": [
    "FARGATE"
    ],
    "networkMode": "awsvpc",
    "cpu": "256",
    "memory": "512",
    "family": "CdkEcsInfraStackTaskDef"
    }

Commit the changes to the Amazon CodeCatalyst repository by issuing the following commands inside the Visual Studio Code IDE terminal window. You will need to update the <your_email> and <your_name> with your email and name.

git config user.email "<your_email>"
git config user.name "<your_name>"
git add .
git commit -m "Initial commit"
git push

In this example, we are using a single task definition file (task.json) which Amazon CodeCatalyst will use to render task definitions in both regions. But, if your workload requires different task definition files across different regions (e.g. region specific resource requirements, compliance requirements, environment specific configurations etc), you can create multiple task definition files in Amazon CodeCatalyst repository and configure RenderAmazonECStaskdefinition action for each regions with different task definition files.

Step 3: Create Amazon CodeCatalyst Workflow for multi-region deployment

Amazon CodeCatalyst workflow is an automated procedure that describes how to build, test, and deploy your code as part of a continuous integration and continuous delivery (CI/CD) system. A workflow defines a series of steps, or actions, to be executed during a workflow run. You can group actions into action groups to keep your workflow organized and configure dependencies between different groups.

  • In the navigation pane, choose CI/CD, and then choose Workflows
  • Choose Create workflow. Select ecs-multi-region-repo from the Source repository dropdown
  • Choose main in the branch. Select Create (Figure 4). The workflow definition file appears in the Amazon CodeCatalyst console’s YAML editor

Create Workflow page in Amazon CodeCatalyst

Figure 4: Create Workflow page in Amazon CodeCatalyst

  • In the YAML editor, you will replace the default content with the below provided workflow definition. Replace <Account_ID> with your AWS account ID.
  • Replace <EcsRegionNameMain>, <EcsClusterNameMain>, <EcsServiceNameMain>, <EcsRegionNameSecondary>, <EcsClusterNameSecondary>, <EcsServiceNameSecondary>. For values with “main” refer to output from workshop-backend-main, and values with “secondary” refer to output from workshop-backend-secondary.
    • Otherwise use your own Amazon ECS Region, Amazon ECS Cluster ARN, Amazon ECS Service Name values.
  • Replace <CodeCatalyst-Dev-Admin-Role> with the Role Name from the pre-requisite
    Name: BuildAndDeployToECS
    SchemaVersion: "1.0"
    
    # Set automatic triggers on code push.
    Triggers:
      - Type: Push
        Branches:
          - main
    
    Actions:
      Build_application_Multi_Region:
            Identifier: aws/build@v1
            Inputs:
              Sources:
                - WorkflowSource
              Variables:
                - Name: region
                  Value: <EcsRegionNameMain>
                - Name: registry
                  Value: <Account_ID>.dkr.ecr.<EcsRegionNameMain>.amazonaws.com
                - Name: image
                  Value: codecatalyst-ecs-image-repo
            Outputs:
              AutoDiscoverReports:
                Enabled: false
              Variables:
                - IMAGE
            Compute:
              Type: EC2
            Environment:
              Connections:
                - Role: <CodeCatalyst-Dev-Admin-Role>
                  Name: "<Account_ID>"
              Name: codecatalyst-ecs-environment
            Configuration:
              Steps:
                - Run: export account=`aws sts get-caller-identity --output text | awk '{ print $1
                    }'`
                - Run: aws ecr get-login-password --region ${region} | docker login --username AWS
                    --password-stdin ${registry}
                - Run: docker build -t appimage app
                - Run: docker tag appimage ${registry}/${image}:${WorkflowSource.CommitId}
                - Run: docker push --all-tags ${registry}/${image}
                - Run: export IMAGE=${registry}/${image}:${WorkflowSource.CommitId}
      build-deploy-region-one:
        Actions:
          RenderAmazonECStaskdefinition_Region_One:
            Identifier: aws/ecs-render-task-definition@v1
            Configuration:
              image: ${Build_application_Multi_Region.IMAGE}
              container-name: web
              task-definition: app/task.json
            Outputs:
              Artifacts:
                - Name: TaskDefinitionOne
                  Files:
                    - task-definition*
            DependsOn:
              - Build_application_Multi_Region
            Inputs:
              Sources:
                - WorkflowSource
          DeploytoAmazonECS_Region_One:
            Identifier: aws/ecs-deploy@v1
            Configuration:
              task-definition: /artifacts/build-deploy-region-one@DeploytoAmazonECS_Region_One/TaskDefinitionOne/${RenderAmazonECStaskdefinition_Region_One.task-definition}
              service: <EcsServiceNameMain>
              cluster: <EcsClusterNameMain>
              region: <EcsRegionNameMain>
            Compute:
              Type: EC2
              Fleet: Linux.x86-64.Large
            Environment:
              Connections:
                - Role: <CodeCatalyst-Dev-Admin-Role>
                  Name: "<Account_ID>"
              Name: codecatalyst-ecs-environment
            DependsOn:
              - RenderAmazonECStaskdefinition_Region_One
            Inputs:
              Artifacts:
                - TaskDefinitionOne
              Sources:
                - WorkflowSource
      build-deploy-region-two:
        DependsOn:
          - build-deploy-region-one
        Actions:
          RenderAmazonECSTaskDefinition_Region_Two:
            # Identifies the action. Do not modify this value.
            Identifier: aws/[email protected]
            # Defines the action's properties.
            Configuration:
              image: ${Build_application_Multi_Region.IMAGE}
              container-name: web
              task-definition: app/task.json
            Outputs:
              Artifacts:
                - Name: TaskDefinitionTwo
                  Files:
                    - task-definition*
            DependsOn:
              - Build_application_Multi_Region
            # Specifies the source and/or artifacts to pass to the action as input.
            Inputs:
              # Optional
              Sources:
                - WorkflowSource # This specifies that the action requires this Workflow as a source
          DeployToAmazonECS_Region_Two:
            Identifier: aws/[email protected] # Defines the action's properties.
            Configuration:
              task-definition: /artifacts/build-deploy-region-two@DeployToAmazonECS_Region_Two/TaskDefinitionTwo/${RenderAmazonECSTaskDefinition_Region_Two.task-definition}
              service: <EcsServiceNameSecondary>
              cluster: <EcsClusterNameSecondary>
              region: <EcsRegionNameSecondary>
            # Required; You can use an environment to access AWS resources.
            Environment:
              Connections:
                - Role: <CodeCatalyst-Dev-Admin-Role>
                  Name: "<Account_ID>"
              Name: codecatalyst-ecs-environment
            DependsOn:
              - RenderAmazonECSTaskDefinition_Region_Two
            # Specifies the source and/or artifacts to pass to the action as input.
            Inputs:
              Artifacts:
                - TaskDefinitionTwo
              # Optional
              Sources:
                - WorkflowSource # This specifies that the action requires this Workflow as a source

Amazon CodeCatalyst Workflow Screen
Figure 5: Amazon CodeCatalyst Workflow Screen

The workflow above (Figure 5) does the following:

  • Whenever code changes are pushed to the repository, a Build action is invoked automatically. The Build action builds a container image and pushes the image to the Amazon Elastic Container Registry (Amazon ECR) repository in the primary region. In this example, we are storing the container image only within the primary region. If you are implementing multi-region for disaster recovery, enable cross-region replication on Amazon ECR to automatically replicate images to repositories in other regions. You will also need to update the task definition files to reference the Amazon ECR repository in the same region where the task will run
  • Once the Build stage is complete, the Amazon ECS task definition is updated with the new Amazon ECR repository image
  • The DeployToECS action then deploys the new image to Amazon ECS in the first region
  • Once the first action group execution succeeds, the Amazon CodeCatalyst workflow invokes second action group repeating the last two steps (Render Task Definition, Deploy) for the second region.

As you may have noticed, the build action is separated from the deployment actions in this example. This way, we are building the container image only once and deploying the same image across multiple regions. But, if you have specific build steps that are region-specific, you can include those actions in the region-specific action groups. This allows for customizations based on regional requirements while maintaining overall consistency.

To check the syntax and structure of your workflow definition:

  • Choose the Validate button. It should add a green banner with “The workflow definition is valid” at the top
  • Select Commit to add the workflow to the repository (Figure 6)

Commit workflow page in Amazon CodeCatalyst
Figure 6: Commit workflow page in Amazon CodeCatalyst

The workflow file is stored in a ~/.codecatalyst/workflows/ folder in the root of your source repository. The file can have a .yml or .yaml extension.

Using the URL of the Application Load Balancer you noted from the pre-requisite from either of the two regions, add /healthcheck to load the health check page in your browser. You’ll to see the message in the health check page as shown in figure 7.

ECS Multi Region Application (US-West-1)

Figure 7: ECS Multi Region Application (US-West-1)

Step 4: Validate the setup

To validate the setup, you will make a small change to the Health check of the sample application.

    • Open Amazon CodeCatalyst dev environment (Visual Studio Code) that you created in Step 1.
    • Update your local copy of the repository. In the terminal run the below command
      git pull

    • Inside the Visual Studio Code IDE, open app.py present inside the app folder.
    • Inside healthcheck() method, on line 13, update the string from ok to ok v1
    • Commit the changes to the repository using the below commands:
      git add . 
      git commit -m “Updating health check static text”
      git push

    After the change is commit, the Amazon CodeCatalyst workflow should start running automatically. Once the Amazon CodeCatalyst workflow finishes execution, paste the Application Load Balancer URL for region and add /healthcheck to reach the check page. You will be able to see the updated message in the health check page as shown in figure 8 and 9.

    ECS Multi Region Application (US-East-1)

    Figure 8: ECS Multi Region Application (US-East-1)

    ECS Multi Region Application (US-West-1)

    Figure 9: ECS Multi Region Application (US-West-1)

    Considerations for multi-region deployments

    In this post, we considered a deployment scenario across two regions. Many organizations have workload running across many regions, serving customers across the globe. The Amazon CodeCatalyst workflow, that we created in this post, can be extended to more than two regions.

    Amazon CodeCatalyst allows fine-grained control for progressive wave-based deployments across multiple regions. This is achieved by using multiple action groups and sequencing those action groups using dependencies in the Amazon CodeCatalyst workflow. For example, in the workflow discussed in Step 3, you defined two action groups build-deploy-region-one and build-deploy-region-two. We setup build-deploy-region-two  to depend on build-deploy-region-one using DependsOn: property, so that the deployment to the second region starts only after the completion of the first region. This approach allows for staggered deployments, mitigating risks by preventing issues in one AWS region from impacting others.

    For workloads spanning multiple regions, the same staggering deployment approach can be extended with more action groups. Each action group can contain a list of regions to deploy to in parallel. Dependencies between action groups ensures the deployment happens sequentially. Below is a high-level architecture (Figure 10) of the setup of 3-stage deployment process for a workload running across 6 regions.

    Staggered Deployment architecture
    Figure 10: Staggered Deployment architecture

    Cleanup

    If you have been following along with the post, you should delete the resources you deployed so you do not continue to incur charges.

    • Manually delete Amazon CodeCatalyst dev environment, source repository and project from your CodeCatalyst Space.
    • Clean up resources created with the CDK
    cdk destroy workshop-backend-secondary
    cdk destroy workshop-backend-main
    cdk destroy workshop-data
    cdk destroy workshop-foundation-secondary
    cdk destroy workshop-foundation-main

    Conclusion

    In conclusion, we demonstrated how you can setup multi-region deployments for Amazon ECS workloads using Amazon CodeCatalyst workflows. We showed how to configure the Amazon CodeCatalyst workflow to deploy to one region at a time, allowing for validation before proceeding to additional regions. The pattern can be extended to more than two AWS regions using additional action groups and dependencies. This solution addresses key challenges in multi-region deployments like maintaining consistency while ensuring high availability. Learn more about multi region in AWS Multi-Region Fundamentals Whitepaper

    Piyush Mattoo

    Piyush Mattoo is a Senior Solution Architect for Financial Services Data Provider segment at Amazon Web Services. He is a software technology leader with over a decade long experience building scalable and distributed software systems to enable business value through the use of technology. He has an educational background in Computer Science with a Masters degree in Computer and Information Science from University of Massachusetts. He is based out of Southern California and current interests include outdoor camping and nature walks.

    William Cardoso

    William Cardoso is a Solutions Architect at Amazon Web Services based in South Florida area. He has 20+ years of experience in designing and developing enterprise systems. He leverages his real world experience in IT operations to work with AWS customers providing architectural and best practice recommendations for new and existing solutions. Outside of work, William enjoys woodworking, walking and cooking for friends and family.

    Hareesh Iyer

    Hareesh Iyer is a Senior Solutions Architect at AWS. He helps customers build scalable, secure, resilient and cost-efficient architectures on AWS. He is passionate about cloud-native patterns, containers and microservices.

How AWS WAF threat intelligence features help protect the player experience for betting and gaming customers

Post Syndicated from Harith Gaddamanugu original https://aws.amazon.com/blogs/security/how-aws-waf-threat-intelligence-features-help-protect-the-player-experience-for-betting-and-gaming-customers/

The betting and gaming industry has grown into a data-rich landscape that presents an enticing target for sophisticated bots. The sensitive personally identifiable information (PII) that is collected and the financial data involved in betting and in-game economies is especially valuable. Microtransactions and in-game purchases are frequently  targeted, making them an ideal case for safeguarding with AWS WAF.

In this blog post, we’ll explore some of these threats in more detail and explain how a layered bot mitigation strategy that uses AWS WAF can minimize the risk and impact of bot activity.

Understanding common automated threats

Automations deployed by threat actors can perform web scraping, perform betting arbitrage to gain an unfair advantage, and use automated techniques to undermine fair competition. Aggressive web scraping can also lead to application overload, service disruptions, and degraded user experience. At AWS, we routinely identify and mitigate automated threats for betting and gaming customers. Some of the common tactics we see in this space include the following:

Scraping tactics

Scraper bots often use fake accounts or compromised credentials to systematically harvest betting odds and other competitive data from multiple sites. A common example of scraping is arbitrage betting, where the scraped data is used to place simultaneous bets in different venues in order to make profits from tiny differences in the asset’s listed price. There are also competitive scraper bots that use this data to improve their betting applications.

Account-related tactics

Account creation fraud aims at claiming sign-up bonuses or other incentives at scale by using bot-generated accounts. Account takeover fraud aims at logging into user accounts to change account details, make purchases, withdraw funds, steal personal information or loyalty points, or use this data to access other accounts on different websites. A common form of this tactic is automated brute force login techniques, such as credential stuffing.

Denial-of-service tactics

Volumetric floods can cause betting and gaming sites to experience slow page-loads, downtime, and damaged brand reputation. DDoS attacks are another common security concern for many customers.

In-game tactics

In-game bots can use automated cheating or expediting techniques to manipulate resources and gain unfair advantages. These bots typically manipulate client applications and make malicious API requests.

AWS WAF intelligent threat mitigation features

To help protect customers from such automated tactics, AWS WAF offers the following intelligent threat mitigation features.

AWS WAF Common Bot Control managed rule group

The AWS WAF Common Bot Control managed rule group uses static analysis to identify web requests and header information that is correlated with known good bots and bad bots. These techniques are helpful in detecting a variety of self-identifying bots, such as web scraping frameworks, search engines, and automated browsers. Using these predetermined patterns and signatures can help gaming customers to identify and block known bot behaviors.

CAPTCHA and challenge rule actions

CAPTCHA rule action – Configured rules in AWS WAF can have a CAPTCHA action. When a rule is configured with a CAPTCHA action, users are required to solve a puzzle to prove that a human being is sending the request. When a user successfully solves a CAPTCHA challenge, a token is placed on their browser so it won’t challenge future requests, using a configurable immunity time. Learn about best practices for configuring CAPTCHA.

Challenge rule action – Challenge scripts run a silent challenge that requires the client session to verify that it’s a browser and not a bot. The verification runs in the background without involving the end user. Challenge-based bot detection can check each visitor’s ability to run JavaScript and store cookies. When a challenge is solved correctly, AWS WAF vends out an AWS WAF token, as seen in Figure 1, which allows bot control to track user activity across sessions. A reduced ability to process these challenges is a sign of bot traffic. The challenge action is a good option for verifying clients that you suspect of being invalid. You can use this feature by setting a selected AWS WAF rule action to CHALLENGE or by using a targeted bot control managed rule group. To learn more about protecting against bots with the AWS WAF challenge and CAPTCHA actions, see this blog post.

Figure 1: A sequence diagram explaining the flow of requests when Challenge is set as a rule action for an AWS WAF rule

Figure 1: A sequence diagram explaining the flow of requests when Challenge is set as a rule action for an AWS WAF rule

Client application integration

AWS WAF provides the following levels of integration.

Intelligent threat integration

To improve the user experience and reduce latency for mobile and API-driven applications, AWS WAF provides client-side application APIs to integrate with your application. These integrations help verify that the client applications that send web requests to your protected resources are the intended clients and that your end users are human beings. This functionality is available for JavaScript and for Android and iOS mobile applications. As shown in Figure 2, the token acquisition process is similar to a challenge action, but slightly different. The basic approach for using the SDK is to create a token provider by using a configuration object, then to use the token provider to retrieve tokens from AWS WAF. By default, the token provider includes the retrieved tokens in your web requests to your protected resource. The intelligent threat integration APIs work with web access control lists (ACLs) that use the intelligent threat rule groups to enable the full functionality of these advanced managed rule groups. You can use the AWS WAF mobile SDKs to implement AWS WAF intelligent threat integration SDKs for Android and iOS mobile applications.

Figure 2: A sequence diagram explaining the flow of requests when AWS WAF intelligent threat mitigation SDKs are configured

Figure 2: A sequence diagram explaining the flow of requests when AWS WAF intelligent threat mitigation SDKs are configured

CAPTCHA JavaScript integration

You can also verify end users by making them solve customized CAPTCHA puzzles that you manage in your application. This is similar to the functionality provided by the AWS WAF CAPTCHA rule action, but with added control over the puzzle placement and behavior. This integration uses the JavaScript intelligent threat integration to run silent challenges and provide AWS WAF tokens to the customer’s page.

AWS WAF Targeted Bot Control

The AWS WAF Targeted Bot Control tier includes the common-level protections described earlier and adds targeted detection for sophisticated bots that don’t self-identify. Targeted protections mitigate bot activity by using a combination of rate limiting and CAPTCHA and background browser challenges. Targeted protections use detection techniques such as the following:

  • Implementing browser fingerprinting – Browser fingerprinting is a powerful tracking and identification technique employed by online gaming sites to gain deep insights into their players’ computing setups. This technique involves probing the unique characteristics and configuration of each gamer’s browser. By collecting dozens of browser data points, a fingerprint can be generated that allows the requests coming from that specific browser to be identified and tracked across gaming sessions. Even if players try to randomize or spoof some browser attributes, perhaps in an attempt to bypass certain restrictions or gain an unfair advantage, the overall fingerprint still allows detection of such attempts. For example, if the user agent claims to be Chrome on Windows but other fingerprint attributes indicate Linux and Firefox, that suggests an attempted spoofing by the player, which can then be flagged by the gaming site’s security measures.

    By using browser fingerprinting and looking for discrepancies, gaming and betting sites gain tools to help detect and block sophisticated bots even when the bots try to mask their true identity and intent. AWS WAF uses tokens for detecting browser inconsistencies, such as when the characteristics of a browser do not match the user agent. The AWS Targeted Bot Control rule group offers this functionality by emitting labels like TGT_SignalBrowserInconsistency, and the recommended mitigation action for inconsistent browsers is to serve a CAPTCHA puzzle.

  • Detecting browser automation – Many threat actors who operate automated programs use scripting languages to carry out their tasks, such as data scraping or launching exploits. They often employ tools that mimic the behavior of a web browser to bypass security measures. To address these challenges, AWS WAF Bot Control offers solutions to help detect and block automated software that simulates browser activity. It uses specific rules like TGT_SignalAutomatedBrowser to examine requests for signs that suggest the browser is not operated by a human, helping to identify and mitigate potential threats from automated systems.
  • Understand normal volumetric activity with unique browser ID tracking – AWS WAF Targeted Bot Control monitors application visitors by assigning each one a unique browser ID (UBID) embedded in a token. It establishes baselines for the number of requests a client sends within a five-minute session and sets three thresholds per device: high, medium, and low. The system identifies clients that exceed normal request rates and challenges them with a CAPTCHA puzzle using the TGT_VolumetricSession rule. For verified bots, the rule group takes no action but labels the traffic with awswaf:managed:aws:bot-control:bot:verified.
  • Using real-time machine learning models for clustering and behavior analysis – Traditional solutions to fight advanced bots faced limitations: handling massive amounts of player traffic, accurately identifying bots without labeling every request (ground truth), and staying cost-effective. To address these challenges, the AWS WAF team created a machine learning model. This model finds hidden bot networks by analyzing patterns in website traffic. It automatically analyzes traffic statistics to identify suspicious activity that suggests coordinated bot activity.

    The model aggregates data at different levels, including the client, session, and behavioral cluster levels. It uses features like session statistics, behavioral cluster information (derived from clustering), and relative entropy to identify suspicious behavior. This feature analyzes web traffic every few minutes and optimizes the analysis for the detection of low intensity, long-duration bots that are distributed across many IP addresses. AWS WAF emits the labels TGT_ML_CoordinatedActivityMedium and TGT_ML_CoordinatedActivityHigh, based on the confidence level of the detection.

    This machine learning capability is included by default in the AWS WAF Targeted Bot Control rules, but you can choose to disable it if needed.

AWS WAF Fraud Control: Account creation fraud prevention

Fraudulent account creation involves the creation of fake accounts for activities such as bonus abuse, impersonation, and phishing. These fake accounts can damage your reputation and expose you to financial fraud. To help prevent account creation fraud, we recommend using the AWS WAF Fraud Control account creation fraud prevention (ACFP) feature. This feature is available in the AWS Managed Rules rule group AWSManagedRulesACFPRuleSet, along with companion application integration SDKs. By integrating this feature into your system, you can effectively monitor and control account creation attempts, helping to provide a safer and more secure environment for your customers.

AWS WAF Fraud Control: Account takeover prevention

Threat actors might try to gain unauthorized access to a player’s account by using stolen credentials, guessing passwords through brute-force exploits, or other means. After they gain access, they can steal money, information, or services, or even pose as the victim to gain access to other accounts. This can lead to financial loss and damage to your reputation. To help prevent account takeovers, we recommend using the AWS WAF Fraud Control account takeover prevention (ATP) feature. This feature is available in the AWS Managed Rules rule group AWSManagedRulesATPRuleSet, along with companion application integration SDKs.

Conclusion

Bot management involves choosing controls to identify traffic coming from bots, and then blocking undesired traffic. The more threat actors are motivated to target a web application, the more they will invest in detection evasion techniques, requiring more advanced mitigation capabilities. We recommend that you adopt a layered approach to managing bots, with differentiated tooling that is adapted to specific bot tactics.

Ready to start putting the tools in place to protect your gaming or betting application from sophisticated bot threats? Check out our solution overview guide for AWS WAF and the Implementing a bot control strategy on AWS whitepaper to learn more about deploying a layered bot mitigation strategy on AWS. You can also sign up for an AWS Activation Day to work directly with our experts on implementing capabilities like AWS WAF, AWS WAF Bot Control, and AWS Shield for your specific use case. For hands-on experience, try our bot mitigation workshops—you can enable managed rule groups like Bot Control in just a few steps. Start your proof-of-concept by contacting your AWS account representative today.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Harith Gaddamanugu
Harith Gaddamanugu

Harith is a Senior Edge Specialist Solutions Architect at AWS, specializing in AWS Perimeter Protection and Edge services. With over a decade of experience in network engineering, content delivery networks, and security, he helps customers improve their application security and performance. Outside of work, Harith enjoys spending time outdoors with friends and family.
Kaustubh Phatak
Kaustubh Phatak

Kaustubh is a seasoned product leader with over 11 years of experience in developing scalable solutions and driving operational excellence. He currently leads the AWS WAF Bot Control and Fraud Control initiatives, where he helps to develop cutting-edge security solutions that protect applications. Kaustubh is passionate about sports, particularly soccer and cricket, and loves spending time with his wife and kid.

Six tips to improve the security of your AWS Transfer Family server

Post Syndicated from John Jamail original https://aws.amazon.com/blogs/security/six-tips-to-improve-the-security-of-your-aws-transfer-family-server/

AWS Transfer Family is a secure transfer service that lets you transfer files directly into and out of Amazon Web Services (AWS) storage services using popular protocols such as AS2, SFTP, FTPS, and FTP. When you launch a Transfer Family server, there are multiple options that you can choose depending on what you need to do. In this blog post, I describe six security configuration options that you can activate to fit your needs and provide instructions for each one.

Use our latest security policy to help protect your transfers from newly discovered vulnerabilities

By default, newly created Transfer Family servers use our strongest security policy, but for compatibility reasons, existing servers require that you update your security policy when a new one is issued. Our latest security policy, including our FIPS-based policy, can help reduce your risks of known vulnerabilities such as CVE-2023-48795, also known as the Terrapin Attack. In 2020, we had already removed support for the ChaCha20-Poly1305 cryptographic construction and CBC with Encrypt-then-MAC (EtM) encryption modes, so customers using our later security policies did not need to worry about the Terrapin Attack. Transfer Family will continue to publish improved security policies to offer you the best possible options to help ensure the security of your Transfer Family servers. See Edit server details for instructions on how to update your Transfer Family server to the latest security policy.

Use slashes in session policies to limit access

If you’re using Amazon Simple Storage Service (Amazon S3) as your data store with a Transfer Family server, the session policy for your S3 bucket grants and limits access to objects in the bucket. Amazon S3 is an object store and not a file system, so it has no concept of directories, only prefixes. You cannot, for example, set permissions on a directory the way you might on a file system. Instead, you set session policies on prefixes.

Even though there isn’t a file system, the slash character still plays an important role. Imagine you have a bucket named DailyReports and you’re trying to authorize certain entities to access the objects in that bucket. If your session policy is missing a slash in the Resource section, such as arn:aws:s3:::$DailyReports*, then you should add a slash to make it arn:aws:s3:::$DailyReports/*. Without the slash (/) before the asterisk (*), your session policy might allow access to buckets you don’t intend. For example, if you also have buckets named DailyReports-archive and DailyReports-testing, then a role with permission arn:aws:s3:::$DailyReports* will also grant access to objects in those buckets, which is probably not what you want. A role with permission arn:aws:s3:::$DailyReports/* won’t grant access to objects in your DailyReports-archive bucket, because the slash (/) makes it clear that only objects whose prefix begins with DailyReports/ will match, and all objects in DailyReports-archive will have a prefix of DailyReports-archive/, which won’t match your pattern. To check to see if this is an issue, follow the instructions in Creating a session policy for an Amazon S3 bucket to find your AWS Identity and Access Management (IAM) session policy.

Use scope down policies to back up logical directory mappings

When creating a logical directory mapping with a role that has more access than you intend to give your users, it’s important to use session policies to tailor the access appropriately. This provides an extra layer of protection against accidental changes to your logical directory mapping opening access to files you didn’t intend.

Details on how to construct a session policy for an S3 bucket can be found in Creating a session policy for an Amazon S3 bucket, and Create fine-grained session permissions using IAM managed policies provides additional context. Amazon S3 also offers IAM Access Analyzer to assist with this process.

Don’t place NLBs in front of a Transfer Family server

We’ve spoken with many customers who have configured a Network Load Balancer (NLB) to route traffic to their Transfer Family server. Usually, they’ve done this either because they created their server before we offered a way to access it from both inside their VPC and from the internet, or to support FTP on the internet. This not only increases the cost for the customer, it can cause other issues, which we describe in this section.

If you’re using this configuration, we encourage you to move to a VPC endpoint and use an Elastic IP. Placing an NLB in front of your Transfer Family server removes your ability to see the source IP of your users, because Transfer Family will see only the IP address of your NLB. This not only degrades your ability to audit who is accessing your server, it can also impact performance. Transfer Family uses the source IP to shard your connections across our data plane. In the case of FTPS, this means that instead of being able to have 10,000 simultaneous connections, a Transfer Family server with an NLB in front of it would be limited to only 300 simultaneous connections. If you have a use case that requires you to place an NLB in front of your Transfer Family server, reach out to the Transfer Family Product Management team through AWS Support or discuss issues on AWS re:Post, so we can look for options to help you take full advantage of our service.

Protect your API Gateway instance with WAF

If you’re using the custom identity provider capability of Transfer Family, you connect your identity provider through Amazon API Gateway. As a best practice, Transfer Family recommends use AWS Web Application Firewall (WAF) to help protect your API Gateway. This will allow you to create access control lists (ACLs) for your API Gateway instance to allow access for only AWS and anyone in the ACL. To help protect your API Gateway instance, see Securing AWS Transfer Family with AWS Web Application Firewall and Amazon API Gateway.

FTPS customers should use TLS session resumption

One of the security challenges with FTPS is that it uses two separate ports to process read/write requests. An analogy to this in the physical world would be going through a drive-thru window where you pay for your food and someone else can cut in front of you to receive your order at the second window. For this reason, security measures have been added to the FTPS protocol over time. In a client-server protocol, there are server-side configurations and client-side configurations.

TLS session resumption helps protect client connections as they hand off between the FTPS control port and the data port. The server sends a unique identifier for each session on the control port, and the client is meant to send that same session identifier back on the data port. This gives the server confidence that it’s talking to the same client on the data port that initiated the session on the control port. Transfer Family endpoints provide three options for session resumption:

  1. Disabled – The server ignores whether the client sends a session ID and doesn’t check that it’s correct, if it is sent. This option exists for backward compatibility reasons, but we don’t recommend it.
  2. Enabled – The server will transmit session IDs and will enforce session IDs if the client uses them, but clients who don’t use session IDs are still allowed to connect. We only recommend this as a transitional state to Enforced to verify client compatibility.
  3. Enforced – Clients must support TLS session resumption, or the server won’t transmit data to them. This is our default and recommended setting.

To use the console to see your TLS session resumption settings:

  1. Sign in to the AWS Management Console in the account where your transfer server runs and go to AWS Transfer Family. Be sure to select the correct AWS Region.
  2. To find your Transfer Family server endpoint, find your Transfer Family server in the console and choose Main Server Details.
  3. Select Additional Details.
  4. Under TLS Session Resumption, you will see if your server is enforcing TLS session resumption.
  5. If some of your users don’t have access to modern FTPS clients that support TLS, you can choose Edit to choose a different option.

Conclusion

Transfer Family offers many benefits to help secure your managed file transfer (MFT) solution as the threat landscape evolves. The steps in this post can help you get the most out of Transfer Family to help protect your file transfers. As the requirements for a secure, compliant architecture for file transfers evolve and threats become more sophisticated, Transfer Family will continue to offer optimized solutions and provide actionable advice on how you can use them. For more information, see Security in AWS Transfer Family and take our self-paced security workshop.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Transfer Family re:Post or contact AWS Support.
 

John Jamail
John Jamail

John is the Head of Engineering for AWS Transfer Family. Prior to joining AWS, he spent eight years working in data security focused on security incident and event monitoring (SIEM), governance, risk, and compliance (GRC), and data loss prevention (DLP).

Refine unused access using IAM Access Analyzer recommendations

Post Syndicated from Stéphanie Mbappe original https://aws.amazon.com/blogs/security/refine-unused-access-using-iam-access-analyzer-recommendations/

As a security team lead, your goal is to manage security for your organization at scale and ensure that your team follows AWS Identity and Access Management (IAM) security best practices, such as the principle of least privilege. As your developers build on AWS, you need visibility across your organization to make sure that teams are working with only the required privileges. Now, AWS Identity and Access Management Analyzer offers prescriptive recommendations with actionable guidance that you can share with your developers to quickly refine unused access.

In this post, we show you how to use IAM Access Analyzer recommendations to refine unused access. To do this, we start by focusing on the recommendations to refine unused permissions and show you how to generate the recommendations and the actions you can take. For example, we show you how to filter unused permissions findings, generate recommendations, and remediate issues. Now, with IAM Access Analyzer, you can include step-by-step recommendations to help developers refine unused permissions quickly.

Unused access recommendations

IAM Access Analyzer continuously analyzes your accounts to identify unused access and consolidates findings in a centralized dashboard. The dashboard helps review findings and prioritize accounts based on the volume of findings. The findings highlight unused IAM roles and unused access keys and passwords for IAM users. For active IAM roles and users, the findings provide visibility into unused services and actions. You can learn more about unused access analysis through the IAM Access Analyzer documentation.

For unused IAM roles, access keys, and passwords, IAM Access Analyzer provides quick links in the console to help you delete them. You can use the quick links to act on the recommendations or use export to share the details with the AWS account owner. For overly permissive IAM roles and users, IAM Access Analyzer provides policy recommendations with actionable steps that guide you to refine unused permissions. The recommended policies retain resource and condition context from existing policies, helping you update your policies iteratively.

Throughout this post, we use an IAM role in an AWS account and configure the permissions by doing the following:

  1. Attaching the AWS managed policy AmazonBedrockReadOnly.
  2. Attaching the AWS managed policy AmazonS3ReadOnlyAccess.
  3. Embedding an inline policy with the permissions described in the following code and named InlinePolicyListLambda.

Content of inline policy InlinePolicyListLambda:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "InlinePolicyLambda",
            "Effect": "Allow",
            "Action": [
                "lambda:ListFunctions",
                "lambda:ListLayers",
                "lambda:ListAliases",
                "lambda:ListFunctionUrlConfigs"
            ],
            "Resource": "*",
            "Condition": {
                "NotIpAddress": {
                    "aws:SourceIp": "1.100.150.200/32"
                }
            }
        }
    ]
}

We use an inline policy to demonstrate that IAM Access Analyzer unused access recommendations are applicable for that use case. The recommendations are also applicable when using AWS managed policies and customer managed policies.

In your AWS account, after you have configured an unused access analyzer, you can select an IAM role that you have used recently and see if there are unused access permissions findings and recommendations.

Prerequisites

Before you get started, you must create an unused access analyzer for your organization or account. Follow the instructions in IAM Access Analyzer simplifies inspection of unused access in your organization to create an unused access analyzer.

Generate recommendations for unused permissions

In this post we explore three options for generating recommendations for IAM Access Analyzer unused permissions findings: the console, AWS CLI, and AWS API.

Generate recommendations for unused permissions using the console

After you have created an unused access analyzer as described in the prerequisites, wait a few minutes to see the analysis results. Then use the AWS Management Console to view the proposed recommendations for the unused permissions.

To list unused permissions findings

  1. Go to the IAM console and under Access Analyzer, choose Unused access from the navigation pane.
  2. Search for active findings with the type Unused permissions in the search box.
    1. Select Active from the Status drop-down list.
    2. In the search box, select Findings type under Properties.
    3. Select Equals as Operators.
    4. Select Findings Type = Unused permissions.
    5. This list shows the active findings for IAM resources with unused permissions.

    Figure 1: Filter on unused permissions in the IAM console

    Figure 1: Filter on unused permissions in the IAM console

  3. Select a finding to learn more about the unused permissions granted to a given role or user.

To obtain recommendations for unused permissions

  1. On the findings detail page, you will see a list of the unused permissions under Unused permissions.
  2. Following that, there is a new section called Recommendations. The Recommendations section presents two steps to remediate the finding:
    1. Review the existing permissions on the resource.
    2. Create new policies with the suggested refined permissions and detach the existing policies.

    Figure 2: Recommendations section

    Figure 2: Recommendations section

  3. The generation of recommendations is on-demand and is done in the background when you’re using the console. The message Analysis in progress indicates that recommendations are being generated. The recommendations exclude the unused actions from the recommended policies.
  4. When an IAM principal, such as an IAM role or user, has multiple permissions policies attached, an analysis of unused permissions is made for each of permissions policies:
    • If no permissions have been used, the recommended action is to detach the existing permissions policy.
    • If some permissions have been used, only the used permissions are kept in the recommended policy, helping you apply the principle of least privilege.
  5. The recommendations are presented for each existing policy in the column Recommended policy. In this example, the existing policies are:
    • AmazonBedrockReadOnly
    • AmazonS3ReadOnlyAccess
    • InlinePolicyListLambda

    And the recommended policies are:

    • None
    • AmazonS3ReadOnlyAccess-recommended
    • InlinePolicyListLambda-recommended

    Figure 3: Recommended policies

    Figure 3: Recommended policies

  6. There is no recommended policy for AmazonBedrockReadOnly because the recommended action is to detach it. When hovering over None, the following message is displayed: There are no recommended policies to create for the existing permissions policy.
  7. AmazonS3ReadOnlyAccess and InlinePolicyListLambda and their associated recommended policy can be previewed by choosing Preview policy.

To preview a recommended policy

IAM Access Analyzer has proposed two recommended policies based on the unused actions.

  1. To preview each recommended policy, choose Preview policy for that policy to see a comparison between the existing and recommended permissions.
    1. Choose Preview policy for AmazonS3ReadOnlyAccess-recommended.
      1. The existing policy has been analyzed and the broad permissions—s3:Get* and s3:List*—have been scoped down to detailed permissions in the recommended policy.
      2. The permissions s3:Describe*, s3-object-lambda:Get*, and s3-object-lambda:List* can be removed because they weren’t used.

      Figure 4: Preview of the recommended policy for AmazonS3ReadOnlyAccess

      Figure 4: Preview of the recommended policy for AmazonS3ReadOnlyAccess

    2. Choose Preview policy for InlinePolicyListLambda-recommended to see a comparison between the existing inline policy InlinePolicyListLambda and its recommended version.
      1. The existing permissions, lambda:ListFunctions and lambda:ListLayers, are kept in the recommended policy, as well as the existing condition.
      2. The permissions in lambda:ListAliases and lambda:ListFunctionUrlConfigs can be removed because they weren’t used.
      Figure 5: Preview the recommended policy for the existing inline policy InlinePolicyListLambda

      Figure 5: Preview the recommended policy for the existing inline policy InlinePolicyListLambda

To download the recommended policies file

  1. Choose Download JSON to download the suggested recommendations locally.

    Figure 6: Download the recommended policies

    Figure 6: Download the recommended policies

  2. A .zip file that contains the recommended policies in JSON format will be downloaded.

    Figure 7: Downloaded recommended policies as JSON files

    Figure 7: Downloaded recommended policies as JSON files

  3. The content of the AmazonS3ReadOnlyAccess-recommended-1-2024-07-22T20/08/44.793Z.json file the same as the recommended policy shown in Figure 4.

Generate recommendations for unused permissions using AWS CLI

In this section, you will see how to generate recommendations for unused permissions using AWS Command Line Interface (AWS CLI).

To list unused permissions findings

  1. Use the following code to refine the results by filtering on the type UnusedPermission and selecting only the active findings. Copy the Amazon Resource Name (ARN) of your unused access analyzer and use it to replace the ARN in the following code:
    aws accessanalyzer list-findings-v2 \
      --analyzer-arn "arn:aws:access-analyzer:<region>:<123456789012>:analyzer/<analyzer_name>" \
      --region <region> \
      --filter '{"findingType": {"eq": ["UnusedPermission"]}, "status": {"eq": ["ACTIVE"]}}'

  2. You will obtain results similar to the following.
    {
        "findings": [
            {
                "analyzedAt": "2024-05-29T07:25:34+00:00",
                "createdAt": "2024-05-23T19:20:59+00:00",
                "id": "0fa3f5a1-bd92-4193-8ca4-aba12cd91370",
                "resource": "arn:aws:iam::123456789012:user/demoIAMUser",
                "resourceType": "AWS::IAM::User",
                "resourceOwnerAccount": "123456789012",
                "status": "ACTIVE",
                "updatedAt": "2024-05-29T07:25:35+00:00",
                "findingType": "UnusedPermission"
            },
            {
                "analyzedAt": "2024-05-29T07:25:34+00:00",
                "createdAt": "2024-05-23T19:20:59+00:00",
                "id": "1e952245-bcf3-48ad-a708-afa460df794b",
                "resource": "arn:aws:iam::123456789012:role/demoIAMRole",
                "resourceType": "AWS::IAM::Role",
                "resourceOwnerAccount": "123456789012",
                "status": "ACTIVE",
                "updatedAt": "2024-05-29T07:25:37+00:00",
                "findingType": "UnusedPermission"
            },
            ...
        ]
    }

To generate unused permissions finding recommendations

After you have a list of findings for unused permissions, you can generate finding recommendations.

  1. Run the following, replacing the analyzer ARN and the finding ID to generate the suggested recommendations.
    aws accessanalyzer generate-finding-recommendation \
      --analyzer-arn "arn:aws:access-analyzer:<region>:<123456789012>:analyzer/<analyzer_name>" \
      --region <region> \
      --id "ab123456-bcd0-78ab-a012-afa460df794b"

  2. You will get an empty response if your command ran successfully. The process is running in the background.

To obtain the generated recommendations

After the recommendations are generated, you need to make a separate API call to view the recommendations details.

  1. The following command returns the recommended remediation.
    aws accessanalyzer get-finding-recommendation \
      --analyzer-arn "arn:aws:access-analyzer:<region>:<123456789012>:analyzer/<analyzer_name>" \
      --region <region> \
      --id "ab123456-bcd0-78ab-a012-afa460df794b"

  2. This command provides the following results. For more information about the meaning and structure of the recommendations, see Anatomy of a recommendation later in this post.

    Note: The recommendations consider AWS managed policies, customer managed policies, and inline policies. The IAM conditions in the initial policy are maintained in the recommendations if the actions they’re related to are used.

    The remediations suggested are to do the following:

    1. Detach AmazonBedrockReadOnly policy because it is unused: DETACH_POLICY
    2. Create a new recommended policy with scoped down permissions from the managed policy AmazonS3ReadOnlyAccess: CREATE_POLICY
    3. Detach AmazonS3ReadOnlyAccess: DETACH_POLICY
    4. Embed a new recommended policy with scoped down permissions from the inline policy: CREATE_POLICY
    5. Delete the inline policy.
    {
        "recommendedSteps": [
            {
                "unusedPermissionsRecommendedStep": {
                    "policyUpdatedAt": "2023-12-06T15:48:19+00:00",
                    "recommendedAction": "DETACH_POLICY",
                    "existingPolicyId": "arn:aws:iam::aws:policy/AmazonBedrockReadOnly"
                }
            },
            {
                "unusedPermissionsRecommendedStep": {
                    "policyUpdatedAt": "2023-08-10T21:31:39+00:00",
                    "recommendedAction": "CREATE_POLICY",
                    "recommendedPolicy": "{\"Version\":\"2012-10-17\",\"Statement\":[{\"Effect\":\"Allow\",\"Action\":[\"s3:GetBucketObjectLockConfiguration\",\"s3:GetBucketOwnershipControls\",\"s3:GetBucketTagging\",\"s3:GetBucketVersioning\",\"s3:GetJobTagging\",\"s3:GetObject\",\"s3:GetObjectAcl\",\"s3:GetObjectLegalHold\",\"s3:GetObjectRetention\",\"s3:GetObjectTagging\",\"s3:GetObjectTorrent\",\"s3:GetObjectVersion*\",\"s3:GetStorage*\",\"s3:ListAllMyBuckets\",\"s3:ListBucket\",\"s3:ListBucketVersions\",\"s3:ListMultipartUploadParts\",\"s3:ListStorageLensGroups\",\"s3:ListTagsForResource\"],\"Resource\":\"*\"}]}",
                    "existingPolicyId": "arn:aws:iam::aws:policy/AmazonS3ReadOnlyAccess"
                }
            },
            {
                "unusedPermissionsRecommendedStep": {
                    "policyUpdatedAt": "2023-08-10T21:31:39+00:00",
                    "recommendedAction": "DETACH_POLICY",
                    "existingPolicyId": "arn:aws:iam::aws:policy/AmazonS3ReadOnlyAccess"
                }
            },
            {
                "unusedPermissionsRecommendedStep": {
                    "recommendedAction": "CREATE_POLICY",
                    "recommendedPolicy": "{\"Version\":\"2012-10-17\",\"Statement\":[{\"Sid\":\"InlinePolicyLambda\",\"Effect\":\"Allow\",\"Action\":[\"lambda:ListFunctions\",\"lambda:ListLayers\"],\"Resource\":\"*\",\"Condition\":{\"NotIpAddress\":{\"aws:SourceIp\":\"1.100.150.200/32\"}}}]}",
                    "existingPolicyId": "InlinePolicyListLambda"
                }
            },
            {
                "unusedPermissionsRecommendedStep": {
                    "recommendedAction": "DETACH_POLICY",
                    "existingPolicyId": "InlinePolicyListLambda"
                }
            }
        ],
        "status": "SUCCEEDED",
        "error": null,
        "completedAt": "2024-07-22T20:40:58.413698+00:00",
        "recommendationType": "UNUSED_PERMISSION_RECOMMENDATION",
        "resourceArn": "arn:aws:iam::123456789012:role/IAMRole_IA2_Blog_EC2Role",
        "startedAt": "2024-07-22T20:40:54+00:00"
    }

Generate recommendations for unused permissions using EventBridge and AWS API

We have described how to use AWS CLI and the console to find unused permissions findings and to generate recommendations.

In this section, we show you how to use an Amazon EventBridge rule to find the active unused permissions findings from IAM Access Analyzer. Then we show you how to generate recommendations using two IAM Access Analyzer APIs to generate the finding recommendations and get the finding recommendations.

To create an EventBridge rule to detect unused permissions findings

Create an EventBridge rule to detect new unused permissions findings from IAM Access Analyzer.

  1. Go to the Amazon EventBridge console.
  2. Choose Rules, and then choose Create rule.
  3. Enter a name for your rule. Leave the Event bus value as the default.
  4. Under Rule type, select Rule with an event pattern.
  5. In the Event Source section, select AWS events or EventBridge partner events.
  6. For Creation method, select Use pattern form.
  7. Under Event pattern:
    1. For Event source, select AWS services.
    2. For AWS service, select Access Analyzer.
    3. For Event type, select Unused Access Finding for IAM entities.

    Note: There is no event for generated recommendations, only for unused access findings.

    Figure 8: Listing unused permissions by filtering events using an EventBridge rule

    Figure 8: Listing unused permissions by filtering events using an EventBridge rule

  8. Configure the Event pattern by changing the default values to the following:
    1. resources: Enter the ARN of your unused access analyzer.
    2. status: ACTIVE indicates that you are only looking for active findings.
    3. findingType: UnusedPermission.
  9. You can select a target Amazon Simple Notification Service (Amazon SNS) to be notified of new active findings for a specific analyzer for unused permissions.

To generate recommendations for unused permissions using the IAM Access Analyzer API

The findings are generated on-demand. For that purpose, IAM Access Analyzer API GenerateFindingRecommendation can be called with two parameters: the ARN of the analyzer and the finding ID.

  1. You can use AWS Software Development Kit (SDK) for Python(boto3) for the API call.
  2. Run the call as follows:
    ia2_client = boto3.client('accessanalyzer')
    response = ia2_client.generate_finding_recommendation(
        analyzerArn=analyzer,
        id=findingId
        )

To obtain the finding recommendations

  1. After the recommendations are generated, they can be obtained by calling the API GetFindingRecommendation with the same parameters: the ARN of the analyzer and the finding ID.
  2. Use AWS SDK for Python (boto3) for the API call as follows:
    ia2_client = boto3.client('accessanalyzer')
    response = ia2_client.get_finding_recommendation(
        analyzerArn=analyzer,
        id=findingId
    )

Remediate based on the generated recommendations

The recommendations are generated as actionable guidance that you can follow. They propose new IAM policies that exclude the unused actions, helping you rightsize your permissions.

Anatomy of a recommendation

The recommendations are usually presented in the following way:

  • Date and time: startedAt, completedAt. Respectively when the API call was made and when the analysis was completed and the results were provided.
  • Resource ARN: The ARN of the resource being analyzed.
  • Recommended steps: The recommended steps, such as creating a new policy based on the actions used and detaching the existing policy.
  • Recommendation type: UNUSED_PERMISSION_RECOMMENDATION.
  • Status: The status of retrieving the finding recommendation. The status values include SUCCEEDED, FAILED, and IN_PROGRESS.

For more information about the structure of recommendations, see the output section of get-finding-recommendation.

Recommended policy review

You must review the recommended policy. The recommended actions depend on the original policy. The original policy will be one of the following:

  • An AWS managed policy: You need to create a new IAM policy using recommendedPolicy. Attach this newly created policy to your IAM role. Then detach the former policy.
  • A customer managed policy or an inline policy: Review the policy, verify its scope, consider how often it’s attached to other principals (customer managed policy only), and when you are confident to proceed, use the recommended policy to create a new policy and detach the former policy.

Use cases to consider when reviewing recommendations

During your review process, keep in mind that the unused actions are determined based on the time defined in your tracking period. The following are some use cases you might have where a necessary role or action might be identified as unused (this is not an exhaustive list of use cases). It’s important to review the recommendations based on your business needs. You can also archive some findings related to the use cases such as the ones that follow:

  • Backup activities: If your tracking period is 28 days and you have a specific role for your backup activities running at the end of each month, you might discover that after 29 days some of the permissions for that backup role are identified as unused.
  • IAM permissions associated to an infrastructure as code deployment pipeline: You should also consider the permissions associated to specific IAM roles such an IAM for infrastructure as code (IaC) deployment pipeline. Your pipeline can be used to deploy Amazon Simple Storage Service (Amazon S3) buckets based on your internal guidelines. After deployment is complete, the pipeline permissions can become unused after your tracking period, but removing those unused permissions can prevent you from updating your S3 buckets configuration or from deleting it.
  • IAM roles associated with disaster recovery activities: While it’s recommended to have a disaster recovery plan, the IAM roles used to perform those activities might be flagged by IAM Access Analyzer for having unused permissions or being unused roles.

To apply the suggested recommendations

Of the three original policies attached to IAMRole_IA2_Blog_EC2Role, AmazonBedrockReadOnly can be detached and AmazonS3ReadOnlyAccess and InlinePolicyListLambda can be refined.

  1. Detach AmazonBedrockReadOnly

    No permissions are used in this policy, and the recommended action is to detach it from your IAM role. To detach it, you can use the IAM console, the AWS CLI, or the AWS API.

  2. Create a new policy called AmazonS3ReadOnlyAccess-recommended and detach AmazonS3ReadOnlyAccess.

    The unused access analyzer has identified unused permissions in the managed policy AmazonS3ReadOnlyAccess and proposed a new policy AmazonS3ReadOnlyAccess-recommended that contains only the used actions. This is a step towards least privilege because the unused actions can be removed by using the recommended policy.

    1. Create a new IAM policy named AmazonS3ReadOnlyAccess-recommended that contains only the following recommended policy or one based on the downloaded JSON file.
      {
        "Version": "2012-10-17",
        "Statement": [
          {
            "Effect": "Allow",
            "Action": [
              "s3:getbuckettagging",
              "s3:getjobtagging",
              "s3:getobject",
              "s3:getobjectacl",
              "s3:getobjectlegalhold",
              "s3:getobjectretention",
              "s3:getobjecttagging",
              "s3:getobjecttorrent",
              "s3:getobjectversion",
              "s3:getobjectversionacl",
              "s3:getobjectversionattributes",
              "s3:getobjectversionforreplication",
              "s3:getobjectversiontagging",
              "s3:getobjectversiontorrent",
              "s3:getstoragelensconfigurationtagging",
              "s3:getstoragelensgroup",
              "s3:listbucket",
              "s3:listbucketversions",
              "s3:listmultipartuploadparts",
              "s3:liststoragelensgroups",
              "s3:listtagsforresource"
            ],
            "Resource": "*"
          }
        ]
      }

    2. Detach the managed policy AmazonS3ReadOnlyAccess.
  3. Embed a new inline policy InlinePolicyListLambda-recommended and delete InlinePolicyListLambda. This inline policy lists AWS Lambda aliases, functions, layers, and function URLs only when coming from a specific source IP address.
    1. Embed the recommended inline policy.

      The recommended policy follows. You can embed an inline policy for the IAM role using the console, AWS CLI, or the AWS API PutRolePolicy.

      {
        "Version": "2012-10-17",
        "Statement": [
          {
            "Sid": "InlinePolicyLambda",
            "Effect": "Allow",
            "Action": [
              "lambda:ListFunctions",
              "lambda:ListLayers"
            ],
            "Resource": "*",
            "Condition": {
              "NotIpAddress": {
                "aws:SourceIp": "1.100.150.200/32"
              }
            }
          }
        ]
      }

    2. Delete the inline policy.
  4. After updating the policies based on the Recommended policy proposed, the finding Status will change from Active to Resolved.

    Figure 9: The finding is resolved

    Figure 9: The finding is resolved

Pricing

There is no additional pricing for using the prescriptive recommendations after you have enabled unused access findings.

Conclusion

As a developer writing policies, you can use the actionable guidance provided in recommendations to continually rightsize your policies to include only the roles and actions you need. You can export the recommendations through the console or set up automated workflows to notify your developers about new IAM Access Analyzer findings.

This new IAM Access Analyzer unused access recommendations feature streamlines the process towards least privilege by selecting the permissions that are used and retaining the resource and condition context from existing policies. It saves an impressive amount of time by the actions used by your principals and guiding you to refine them.

By using the IAM Access Analyzer findings and access recommendations, you can quickly see how to refine the permissions granted. We have shown in this blog post how to generate prescriptive recommendations with actionable guidance for unused permissions using AWS CLI, API calls, and the console.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

P. Stéphanie Mbappe

P. Stéphanie Mbappe
Stéphanie is a Security Consultant with Amazon Web Services. She delights in assisting her customers at any step of their security journey. Stéphanie enjoys learning, designing new solutions, and sharing her knowledge with others.

Mathangi Ramesh

Mathangi Ramesh
Mathangi is the product manager for AWS Identity and Access Management. She enjoys talking to customers and working with data to solve problems. Outside of work, Mathangi is a fitness enthusiast and a Bharatanatyam dancer. She holds an MBA degree from Carnegie Mellon University.

Using Amazon Detective for IAM investigations

Post Syndicated from Ahmed Adekunle original https://aws.amazon.com/blogs/security/using-amazon-detective-for-iam-investigations/

Uncovering  AWS Identity and Access Management (IAM) users and roles potentially involved in a security event can be a complex task, requiring security analysts to gather and analyze data from various sources, and determine the full scope of affected resources.

Amazon Detective includes Detective Investigation, a feature that you can use to investigate IAM users and roles to help you determine if a resource is involved in a security event and obtain an in-depth analysis. It automatically analyzes resources in your Amazon Web Services (AWS) environment using machine learning and threat intelligence to identify potential indicators of compromise (IoCs) or suspicious activity. This allows analysts to identify patterns and identify which resources are impacted by security events, offering a proactive approach to threat identification and mitigation. Detective Investigation can help determine if IAM entities have potentially been compromised or involved in known tactics, techniques, and procedures (TTPs) from the MITRE ATT&CK framework, a well adopted framework for security and threat detection. MITRE TTPs are the terms used to describe the behaviors, processes, actions, and strategies used by threat actors engaged in cyberattacks.

In this post, I show you how to use Detective Investigation and how to interpret and use the information provided from an IAM investigation.

Prerequisites

The following are the prerequisites to follow along with this post:

Use Detective Investigation to investigate IAM users and roles

To get started with an investigation, sign in to the console. The walkthrough uses three scenarios:

  1. Automated investigations
  2. Investigator persona
  3. Threat hunter persona

In addition to Detective, some of these scenarios also use Amazon GuardDuty, which is an intelligent threat detection service.

Scenario 1: Automated investigations

Automatic investigations are available in Detective. Detective only displays investigation information when you’re running an investigation. You can use the Detective console to see the number of IAM roles and users that were impacted by security events over a set period. In addition to the console, you can use the StartInvestigation API to initiate a remediation workflow or collect information about IAM entities involved or AWS resources compromised.

The Detective summary dashboard, shown in Figure 1, automatically shows you the number of critical investigations, high investigations, and the number of IAM roles and users found in suspicious activities over a period of time. Detective Investigation uses machine learning models and threat intelligence to surface only the most critical issues, allowing you to focus on high-level investigations. It automatically analyzes resources in your AWS environment to identify potential indicators of compromise or suspicious activity.

To get to the dashboard using the Detective console, choose Summary from the navigation pane.

Figure 1: AWS roles and users impacted by a security event

Figure 1: AWS roles and users impacted by a security event

Note: If you don’t have automatic investigations listed in Detective, the View active investigations link won’t display any information. To run a manual investigation, follow the steps in Running a Detective Investigation using the console or API.

If you have an active automatic investigation, choose View active investigations on the Summary dashboard to go to the Investigations page (shown in Figure 2), which shows potential security events identified by Detective. You can select a specific investigation to view additional details in the investigations report summary.

Figure 2: Active investigations that are related to IAM entities

Figure 2: Active investigations that are related to IAM entities

Select a report ID to view its details. Figure 3 shows the details of the selected event under Indicators of compromise along with the AWS role that was involved, period of time, role name, and the recommended mitigation action. The indicators of compromise list includes observed tactics from the MITRE ATT&CK framework, flagged IP addresses involved in potential compromise (if any), impossible travel under the indicators, and the finding group. You can continue your investigation by selecting and reviewing the details of each item from the list of indicators of compromise.

Figure 3: Summary of the selected investigation

Figure 3: Summary of the selected investigation

Figure 4 shows the lower portion of the selected investigation. Detective maps the investigations to TTPs from the MITRE ATT&CK framework. TTPs are classified according to their severity. The console shows the techniques and actions used. When selecting a specific TTP, you can see the details in the right pane. In this example, the valid cloud credential has IP addresses involved in 34 successful API call attempts.

Figure 4: TTP mappings

Figure 4: TTP mappings

Scenario 2: Investigator persona

For this scenario, you have triaged the resources associated with a GuardDuty finding informing you that an IAM user or role has been identified in an anomalous behavior. You need to investigate and analyze the impact this security issue might have had on other resources and ensure that nothing else needs to be remediated.

The example for this use case starts by going to the GuardDuty console and choosing Findings from the navigation pane, selecting a GuardDuty IAM finding, and then choosing the Investigate with Detective link.

Figure 5: List of findings in GuardDuty

Figure 5: List of findings in GuardDuty

Let’s now investigate an IAM user associated with the GuardDuty finding. As shown in Figure 6, you have multiple options for pivoting to Detective, such as the GuardDuty finding itself, the AWS account, the role session, and the internal and external IP addresses.

Figure 6: Options for pivoting to Detective

Figure 6: Options for pivoting to Detective

From the list of Detective options, you can choose Role session, which will help you investigate the IAM role session that was in use when the GuardDuty finding was created. Figure 7 shows the IAM role session page.

Before moving on to the next section, you would scroll down to Resources affected in the GuardDuty finding details panel on the right side of the screen and take note of the Principal ID.

Figure 7: IAM role session page in Detective

Figure 7: IAM role session page in Detective

A role session consists of an instantiation of an IAM role and the associated set of short-term credentials. A role session involves the following:

When investigating a role session, consider the following questions:

  • How long has the role been active?
  • Is the role routinely used?
  • Has activity changed over that use?
  • Was the role assumed by multiple users?
  • Was it assumed by a large number of users? A narrowly used role session might guide your investigation differently from a role session with overlapping use.

You can use the principal ID to get more in-depth details using the Detective search function. Figure 8 shows the search results of an IAM role’s details. To use the search function, choose Search from the navigation pane, select Role session as the type, and enter an exact identifier or identifier with wildcard characters to search for. Note that the search is case sensitive.

When you select the assumed role link, additional information about the IAM role will be displayed, helping to verify if the role has been involved in suspicious activities.

Figure 8: Results of an IAM role details search

Figure 8: Results of an IAM role details search

Figure 9 shows other findings related to the role. This information is displayed by choosing the Assumed Role link in the search results.

Now you should see a new screen with information specific to the role entity that you selected. Look through the role information and gather evidence that would be important to you if you were investigating this security issue.

Were there other findings associated to the role? Was there newly observed activity during this time in terms of new behavior? Were there resource interaction associated with the role? What permissions did this role have?

Figure 9: Other findings related to the role

Figure 9: Other findings related to the role

In this scenario, you used Detective to investigate an IAM role session. The information that you have gathered about the security findings will help give you a better understanding of other resources that need to be remediated, how to remediate, permissions that need to be scoped down, and root cause analysis insight to include in your action reports.

Scenario 3: Threat hunter persona

Another use case is to aid in threat hunting (searching) activities. In this scenario, suspicious activity has been detected in your organization and you need to find out what resources (that is, what IAM entities) have been communicating with a command-and-control IP address. You can check from the Detective summary page for roles and users with the highest API call volume, which automatically lists the IAM roles and users that were impacted by security events over a set time scope, as shown in Figure 10.

Figure 10: Roles and users with the highest API call volume

Figure 10: Roles and users with the highest API call volume

From the list of Principal (role or user) options, choose the user or role that you find interesting based on the data presented. Things to consider when choosing the role or user to examine:

  • Is there a role with a large amount of failed API calls?
  • Is there a role with an unusual data trend?

After choosing a role from the DetectiveSummary page, you’re taken to the role overview page. Scroll down to the Overall API call volume section to view the overall volume of API calls issued by the resource during the scope time. Detective presents this information to you in a graphical interface without the need to create complex queries.

Figure 11: Graph showing API call volume

Figure 11: Graph showing API call volume

In the Overall API call volume, choose the display details for time scope button at the bottom of the section to search through the observed IP addresses, API method by service, and resource.

Figure 12: <strong>Overall API call volume</strong> during the specified scope time” width=”780″ class=”size-full wp-image-35810″ style=”border: 1px solid #bebebe”></p>
<p id=Figure 12: Overall API call volume during the specified scope time

To see the details for a specific IP address, use the Overall API call volume panel to search through different locations and to determine where the failed API calls came from. Select an IP address to get more granular details (as shown in Figure 13). When looking through this information, think about what this might tell you in your own environment.

  • Do you know who normally uses this role?
  • What is this role used for?
  • Should this role be making calls from various geolocations?
Figure 13: Granular details for the selected IP address

Figure 13: Granular details for the selected IP address

In this scenario, you used Detective to review potentially suspicious activity in your environment related to information assumed to be malicious. If adversaries have assumed the same role with different session names, this gives you more information about how this IAM role was used. If you find information related to the suspicious resources in question, you should conduct a formal search according to your internal incident response playbooks.

Conclusion

In this blog post, I walked you through how to investigate IAM entities (IAM users or rules) using Amazon Detective. You saw different scenarios on how to investigate IAM entities involved in a security event. You also learned about the Detective investigations for IAM feature, which you can use to automatically investigate IAM entities for indicators of compromise (IOCs), helping security analysts determine whether IAM entities have potentially been compromised or involved in known TTPs from the MITRE ATT&CK framework.

There’s no additional charge for this capability, and it’s available today for existing and new Detective customers in AWS Regions that support Detective. If you don’t currently use Detective, you can start a free 30-day trial. For more information about Detective investigations, see Detective Investigation.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Ahmed Adekunle
Ahmed Adekunle

Ahmed is a Security Specialist Solutions Architect focused on detection and response services at AWS. Before AWS, his background was in business process management and AWS tech consulting, helping customers use cloud technology to transform their business. Outside of work, Ahmed enjoys playing soccer, supporting less privileged activities, traveling, and eating spicy food, specifically African cuisine.

Get to know Amazon GuardDuty Runtime Monitoring for Amazon EC2

Post Syndicated from Scott Ward original https://aws.amazon.com/blogs/security/get-to-know-amazon-guardduty-runtime-monitoring-for-amazon-ec2/

In this blog post, I take you on a deep dive into Amazon GuardDuty Runtime Monitoring for EC2 instances and key capabilities that are part of the feature. Throughout the post, I provide insights around deployment strategies for Runtime Monitoring and detail how it can deliver security value by detecting threats against your Amazon Elastic Compute Cloud (Amazon EC2) instances and the workloads you run on them. This post builds on the post by Channy Yun that outlines how to enable Runtime Monitoring, how to view the findings that it produces, and how to view the coverage it provides across your EC2 instances.

Amazon Web Services (AWS) launched Amazon GuardDuty at re:Invent 2017 with a focus on providing customers managed threat detection capabilities for their AWS accounts and workloads. When enabled, GuardDuty takes care of consuming and processing the necessary log data. Since its launch, GuardDuty has continued to expand its threat detection capabilities. This expansion has included identifying new threat types that can impact customer environments, identifying new threat tactics and techniques within existing threat types and expanding the log sources consumed by GuardDuty to detect threats across AWS resources. Examples of this expansion include the ability to detect EC2 instance credentials being used to invoke APIs from an IP address that’s owned by a different AWS account than the one that the associated EC2 instance is running in, and the ability to identify threats to Amazon Elastic Kubernetes Services (Amazon EKS) clusters by analyzing Kubernetes audit logs.

GuardDuty has continued to expand its threat detection capabilities beyond AWS log sources, providing a more comprehensive coverage of customers’ AWS resources. Specifically, customers needed more visibility around threats that might occur at the operating system level of their container and compute instances. To address this customer need, GuardDuty released the Runtime Monitoring feature, beginning with support on Amazon Elastic Kubernetes Service (Amazon EKS) workloads. Runtime Monitoring provides operating system insight for GuardDuty to use in detecting potential threats to workloads running on AWS and enabled the operating system visibility that customers were asking for. At re:Invent 2023, GuardDuty expanded Runtime Monitoring to include Amazon Elastic Container Service (Amazon ECS)—including serverless workloads running on AWS Fargate, and previewed support for Amazon EC2, which became generally available earlier this year. The release of EC2 Runtime Monitoring enables comprehensive compute coverage for GuardDuty across containers and EC2 instances, delivering breadth and depth for threat detection in these areas.

Features and functions

GuardDuty EC2 Runtime Monitoring relies on a lightweight security agent that collects operating system events—such as file access, processes, command line arguments, and network connections—from your EC2 instance and sends them to GuardDuty. After the operating system events are received by GuardDuty, they’re evaluated to identify potential threats related to the EC2 instance. In this section, we explore how GuardDuty is evaluating the runtime events it receives and how GuardDuty presents identified threat information.

Command arguments and event correlation

The runtime security agent enables GuardDuty to create findings that can’t be created using the foundational data sources of VPC Flow Logs, DNS logs, and CloudTrail logs. The security agent can collect detailed information about what’s happening at the instance operating system level that the foundational data sources don’t contain.

With the release of EC2 Runtime Monitoring, additional capabilities have been added to the runtime agent and to GuardDuty. The additional capabilities include collecting command arguments and correlation of events for an EC2 instance. These new capabilities help to rule out benign events and more accurately generate findings that are related to activities that are associated with a potential threat to your EC2 instance.

Command arguments

The GuardDuty security agent collects information on operating system runtime commands (curl, systemctl, cron, and so on) and uses this information to generate findings. The security agent now also collects the command arguments that were used as part of running a command. This additional information gives GuardDuty more capabilities to detect threats because of the additional context related to running a command.

For example, the agent will not only identify that systemctl (which is used to manage services on your Linux instance) was run but also which parameters the command was run with (stop, start, disable, and so on) and for which service the command was run. This level of detail helps identify that a threat actor might be changing security or monitoring services to evade detection.

Event correlation

GuardDuty can now also correlate multiple events collected using the runtime agent to identify scenarios that present themselves as a threat to your environment. There might be events that happen on your instance that, on their own, don’t present themselves as a clear threat. These are referred to as weak signals. However, when these weak signals are considered together and the sequence of commands aligns to malicious activity, GuardDuty uses that information to generate a finding. For example, a download of a file would present itself as a weak signal. If that download of a file is then piped to a shell command and the shell command begins to interact with additional operating system files or network configurations, or run known malware executables, then the correlation of all these events together can lead to a GuardDuty finding.

GuardDuty finding types

GuardDuty Runtime Monitoring currently supports 41 finding types to indicate potential threats based on the operating system-level behavior from the hosts and containers in your Amazon EKS clusters on Amazon EC2, Amazon ECS on Fargate and Amazon EC2, and EC2 instances. These findings are based on the event types that the security agent collects and sends to the GuardDuty service.

Five of these finding types take advantage of the new capabilities of the runtime agent and GuardDuty, which were discussed in the previous section of this post. These five new finding types are the following:

Each GuardDuty finding begins with a threat purpose, which is aligned with MITRE ATT&CK tactics. The Execution finding types are focused on observed threats to the actual running of commands or processes that align to malicious activity. The DefenseEvasion finding types are focused on situations where commands are run that are trying to disable defense mechanisms on the instance, which would normally be used to identify or help prevent the activity of a malicious actor on your instance.

In the following sections, I go into more detail about the new Runtime Monitoring finding types and the types of malicious activities that they are identifying.

Identifying suspicious tools and commands

The SuspiciousTool, SuspiciousCommand, and PtraceAntiDebugging finding types are focused on suspicious activities, or those that are used to evade detection. The approach to identify these types of activities is similar. The SuspiciousTool finding type is focused on tools such as backdoor tools, network scanners, and network sniffers. GuardDuty helps to identify the cases where malicious activities related to these tools are occurring on your instance.

The SuspiciousCommand finding type identifies suspicious commands with the threat purposes of DefenseEvasion or Execution. The DefenseEvasion findings are an indicator of an unauthorized user trying to hide their actions. These actions could include disabling a local firewall, modifying local IP tables, or removing crontab entries. The Execution findings identify when a suspicious command has been run on your EC2 instance. The findings related to Execution could be for a single suspicious command or a series of commands, which, when combined with a series of other commands along with additional context, becomes a clearer indicator of suspicious activity. An example of an Execution finding related to combining multiple commands could be when a file is downloaded and is then run in a series of steps that align with a known malicious pattern.

For the PtraceAntiDebugging finding, GuardDuty is looking for cases where a process on your instance has used the ptrace system call with the PTRACE_TRACEME option, which causes an attached debugger to detach from the running process. This is a suspicious activity because it allows a process to evade debugging using ptrace and is a known technique that malware uses to evade detection.

Identifying running malicious files

The updated GuardDuty security agent can also identify when malicious files are run. With the MaliciousFileExecuted finding type, GuardDuty can identify when known malicious files might have been run on your EC2 instance, providing a strong indicator that malware is present on your instance. This capability is especially important because it allows you to identify known malware that might have been introduced since your last malware scan.

Finding details

All of the findings mentioned so far are consumable through the AWS Management Console for GuardDuty, through the GuardDuty APIs, as Amazon EventBridge messages, or through AWS Security Hub. The findings that GuardDuty generates are meant to not only tell you that a suspicious event has been observed on your instance, but also give you enough context to formulate a response to the finding.

The GuardDuty security agent collects a variety of events from the operating system to use for threat detection. When GuardDuty generates a finding based on observed runtime activities, it will include the details of these observed events, which can help with confirmation on what the threat is and provide you a path for possible remediation steps based on the reported threat. The information provided in a GuardDuty runtime finding can be broken down into three main categories:

  • Information about the impacted AWS resource
  • Information about the observed processes that were involved in the activity
  • Context related to the runtime events that were observed

Impacted AWS resources

In each finding that GuardDuty produces, information about the impacted AWS resource will be included. For EC2 Runtime Monitoring, the key information included will be information about the EC2 instance (such as name, instance type, AMI, and AWS Region), tags that are assigned to the instance, network interfaces, and security groups. This information will help guide your response and investigation to the specific instance that’s identified for the observed threat. It’s also useful in assessing key network configurations of the instance that could assist with confirming whether the network configuration of the instance is correct or assessing how the network configuration might factor into the response.

Process details

For each runtime finding, GuardDuty includes the details that were observed about the process attributed to the threat that the finding is for. Common items that you should expect to see include the name of the executable and the path to the executable that resulted in the finding being created, the ID of the operating system process, when the process started, and which operating system user ran the process. Additionally, process lineage is included in the finding. Process lineage helps identify operating system processes that are related to each other and provides insight into the parent processes that were run leading up to the identified process. Understanding this lineage can give you valuable insight into what the root cause of the malicious process identified in the finding might be; for example, being able to identify which other commands were run that ultimately led to the activation of the executable or command identified in the finding. If the process attributed to the finding is running inside a container, the finding also provides container details such as the container ID and image.

Runtime context

Runtime context provides insight on things such as file system type, flags that were used to control the behavior of the event, name of the potentially suspicious tool, path to the script that generated the finding, and the name of the security service that was disabled. The context information in the finding is intended to help you further understand the runtime activity that was identified as a threat and determine its potential impact and what your response might be. For example, a command that is detected by using the systemctl command to disable the apparmor utility would report the process information related to running the systemctl command, and then the runtime context would contain the name of the actual service that was impacted by the systemctl command call and the options used with the command.

See Runtime Monitoring finding details for a full list of the process and context details that might be present in your runtime findings.

Responding to runtime findings

With GuardDuty findings, it’s a best practice to enable an event-based response that can be invoked as soon as the runtime finding is generated. This approach holds true for runtime related findings as well. For every runtime finding that GuardDuty generates, a copy of the finding is sent to EventBridge. If you use Security Hub, a copy of the finding is sent to Security Hub as well. With EventBridge, you can define a rule with a pattern that matches the finding attributes you want to prioritize and respond to. This pattern could be very broad in looking for all runtime-related findings. Or, it could be more specific, only looking for certain finding types, findings of a certain severity, or even certain attributes related to the process or runtime context of a finding.

After the rule pattern is established, you can define a target that the finding should be sent to. This target can be one of over 20 AWS services, which gives you lots of flexibility in routing the finding into the operational tools or processes that are used by your company. The target could be an AWS Lambda function that’s responsible for evaluating the finding, adding some additional data to the finding, and then sending it to a ticketing or chat tool. The target could be an AWS Systems Manager runbook, which would be used on the actual operating system to perform additional forensics or to isolate or disable any processes that are identified in the finding.

Many customers take a stepped approach in their response to GuardDuty findings. The first step might be to make sure that the finding is enriched with as many supporting details as possible and sent to the right individual or team. This helps whoever’s investigating the finding to confirm that the finding is a true positive, further informing the decision on what action to take.

In addition to having an event-based response to GuardDuty findings, you can investigate each GuardDuty runtime finding in the GuardDuty or Security Hub console. Through the console, you can research the details of the finding and use the information to inform the next steps to respond to or remediate the finding.

Speed to detection

With its close proximity to your workloads, the GuardDuty security agent can produce findings more quickly when compared to processing log sources such as VPC Flow Logs and DNS logs. The security agent collects operating system events and forwards them directly to the GuardDuty service, examining events and generating findings more quickly. This helps you to formulate a response sooner so that you can isolate and stop identified threats to your EC2 instances.

Let’s examine a finding type that can be detected by both the runtime security agent and by the foundational log sources of AWS CloudTrail, VPC Flow Logs, and DNS logs. Backdoor:EC2/C&CActivity.B!DNS and Backdoor:Runtime/C&CActivity.B!DNS are the same finding with one coming from DNS logs and one coming from the runtime security agent. While GuardDuty doesn’t have a service-level agreement (SLA) on the time it takes to consume the findings for a log source or the security agent, testing for these finding types reveals that the runtime finding is generated in just a few minutes. Log file-based findings will take around 15 minutes to produce because of the latency of log file delivery and processing. In the end, these two findings mean the same thing, but the runtime finding will arrive faster and with additional process and context information, helping you implement a response to the threat sooner and improve your ability to isolate, contain, and stop the threat.

Runtime data and flow logs data

When exploring the Runtime Monitoring feature and its usefulness for your organization, a key item to understand is the foundational level of protection for your account and workloads. When you enable GuardDuty the foundational data sources of VPC Flow Logs, DNS logs, and CloudTrail logs are also enabled, and those sources cannot be turned off without fully disabling GuardDuty. Runtime Monitoring provides contextual information that allows for more precise findings that can help with targeted remediation compared to the information provided in VPC Flow Logs. When the Runtime Monitoring agent is deployed onto an instance, the GuardDuty service still processes the VPC Flow Logs and DNS logs for that instance. If, at any point in time, an unauthorized user tampers with your security agent or an instance is deployed without the security agent, GuardDuty will continue to use VPC Flow Logs and DNS logs data to monitor for potential threats and suspicious activity, providing you defense in depth to help ensure you have visibility and coverage for detecting threats.

Note: GuardDuty doesn’t charge you for processing VPC Flow Logs while the Runtime Monitoring agent is active on an instance.

Deployment strategies

There are multiple strategies that you can use to install the GuardDuty security agent on an EC2 instance, and it’s important to use the one that fits best based on how you deploy and maintain instances in your environment. The following are agent installation options that cover managed installation, tag-based installation, and manual installation techniques. The managed installation approach is a good fit for most customers, but the manual options are potentially better if you have existing processes that you want to maintain or you want the more fine-grained features provided by agent installation compared to the managed approach.

Note: GuardDuty requires that each VPC, with EC2 instances running the GuardDuty agent, has a VPC endpoint that allows the agent to communicate with the GuardDuty service. You aren’t charged for the cost of these VPC endpoints. When you’re using the GuardDuty managed agent feature, GuardDuty will automatically create and operate these VPC endpoints for you. For the other agent deployment options listed in this section, or other approaches that you take, you must manually configure the VPC endpoint for each VPC where you have EC2 instances that will run the GuardDuty agent. See Creating VPC endpoint manually for additional details.

GuardDuty-managed installation

If you want to use security agents to monitor runtime activity on your EC2 instances but don’t want to manage the installation and lifecycle of the agent on specific instances, then Automated agent configuration is the option for you. For GuardDuty to successfully manage agent installation, each EC2 instance must meet the operating system architectural requirements of the security agent. Additionally, each instance must have the Systems Manager agent installed and configured with the minimal instance permissions that System Manager requires.

In addition to making sure that your instances are configured correctly, you also need to enable automated agent configuration for your EC2 instances in the Runtime Monitoring section of the GuardDuty console. Figure 1 shows what this step looks like.

Figure 1: Enable GuardDuty automated agent configuration for Amazon EC2

Figure 1: Enable GuardDuty automated agent configuration for Amazon EC2

After you have enabled automated agent configuration and have your instances correctly configured, GuardDuty will install and manage the security agent for every instance that is configured.

GuardDuty-managed with explicit tagging

If you want to selectively manage installation of the GuardDuty agent but still want automated deployment and updates, you can use inclusion or exclusion tags to control which instances the agent is installed to.

  • Inclusion tags allow you to specify which EC2 instances the GuardDuty security agent should be installed to without having to enable automated agent configuration. To use inclusion tags, each instance where the security agent should be installed needs to have a key-value pair of GuardDutyManaged/true. While you don’t need to turn on automated agent configuration to use inclusion tags, each instance that you tag for agent installation needs to have the Systems Manager agent installed and the appropriate permissions attached to the instance using an instance role.
  • Exclusion tags allow you to enable automated agent configuration, and then selectively manage which instances the agent shouldn’t be deployed to. To use exclusion tags, each instance that shouldn’t have an instance installed needs to have a key-value pair of GuardDutyManaged/false.

You can use selective installation for a variety of use cases. If you’re doing a proof of concept with EC2 Runtime Monitoring, you might want to deploy the solution to a subset of your instances and then gradually onboard additional instances. At times, you might want to limit agent installation to instances that are deployed into certain environments or applications that are a priority for runtime monitoring. Tagging resources associated with these workloads helps ensure that monitoring is in place for resources that you want to prioritize for runtime monitoring. This strategy gives you more fine-grained control but also requires more work and planning to help ensure that the strategy is implemented correctly.

With a tag-based strategy it is important to understand who is allowed to add or remove tags to your EC2 instances as this influences when security controls are enabled or disabled. A review of your IAM roles and policies for tagging permissions is recommended to help ensure that the appropriate principals have access to this tagging capability. This IAM document provides an example of how you may limit tagging capabilities within a policy. The approach you take will depend on how you are using policies within your environment.

Manual agent installation options

If you don’t want to run the Systems Manager agent that powers the automated agent configuration, or if you have your own strategy to install and configure software on your EC2 instances, there are other deployment options that are better suited for your situation. The following are multiple approaches that you can use to manually install the GuardDuty agent for Runtime Monitoring. See Installing the security agent manually for general pointers on the recommended manual installation steps. With manual installation, you’re responsible for updating the GuardDuty security agent when new versions of the agent are released. Updating the agent can often be performed using the same techniques as installing the agent.

EC2 Image Builder

Your EC2 deployment strategy might be to build custom Amazon EC2 machine images that are then used as the approved machine images for your organization’s workloads. One option for installing the GuardDuty runtime agent as part of a machine image build is to use EC2 Image Builder. Image Builder simplifies the building, testing, and deployment of virtual machine and container images for use on AWS. With Image Builder, you define an image pipeline that includes a recipe with a build component for installing the GuardDuty Runtime Monitoring RPM. This approach with Image Builder helps ensure that your pre-built machine image includes the necessary components for EC2 Runtime Monitoring so that the necessary security monitoring is in place as soon as your instances are launched.

Bootstrap

Some customers prefer to configure their EC2 instances as they’re launched. This is commonly done through the user data field of an EC2 instance definition. For EC2 Runtime Monitoring agent installation, you would add the steps related to download and install of the runtime RPM as part of your user data script. The steps that you would add to your user data script are outlined in the Linux Package Managers method of Installing the security agent manually.

Other tools

In addition to the preceding steps, there are other tools that you can use when you want to incorporate the installation of the GuardDuty runtime monitoring agent. Tools such as Packer for building EC2 images, and Ansible, Chef, and Puppet for instance automation can be used to run the necessary steps to install the runtime agent onto the necessary EC2 instances. See Installing the security agent manually for guidance on the installation commands you would use with these tools.

Conclusion

Through customer feedback, GuardDuty has enhanced its threat detection capabilities with the Runtime Monitoring feature and you can now use it to deploy the same security agent across different compute services in AWS for runtime threat detection. Runtime monitoring provides an additional level of visibility that helps you achieve your security goals for your AWS workloads.

This post outlined the GuardDuty EC2 Runtime Monitoring feature, how you can implement the feature on your EC2 instances, and the security value that the feature provides. The insight provided in this post is intended to help you better understand how EC2 Runtime Monitoring can benefit you in achieving your security goals related to identifying and responding to threats.

To learn more about GuardDuty and its Runtime Monitoring capabilities, see Runtime Monitoring in GuardDuty.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
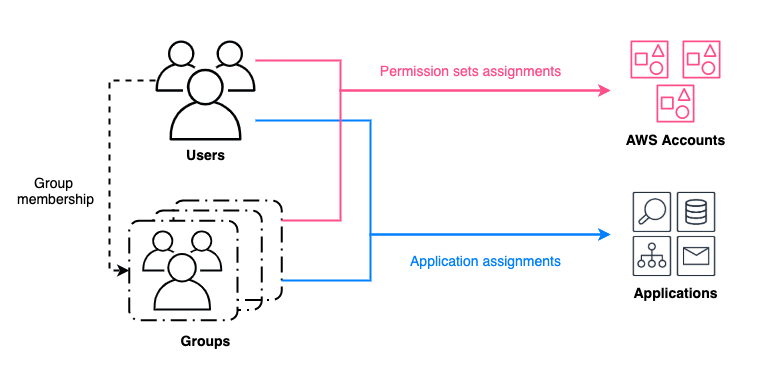
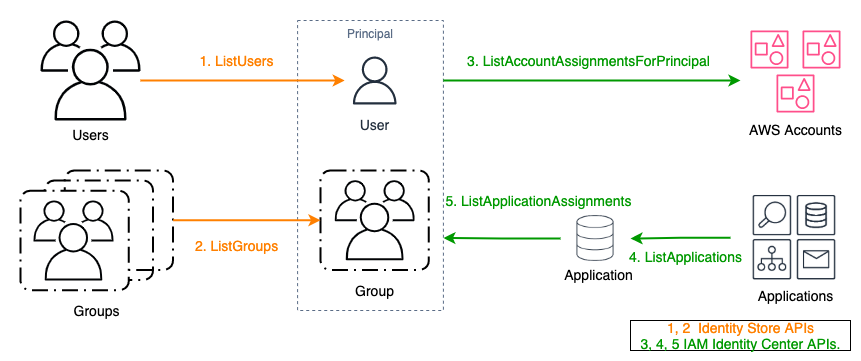
Scott Ward


Scott Ward

Scott is a Principal Solutions Architect with the External Security Services (ESS) product team and has been with Amazon for over 20 years. Scott provides technical guidance to customers on how to use security services to protect their AWS environments. Past roles include technical lead for the AWS Security Partner segment and member of the Amazon.com global financial systems technical team.

Use Batch Processing Gateway to automate job management in multi-cluster Amazon EMR on EKS environments

Post Syndicated from Umair Nawaz original https://aws.amazon.com/blogs/big-data/use-batch-processing-gateway-to-automate-job-management-in-multi-cluster-amazon-emr-on-eks-environments/

AWS customers often process petabytes of data using Amazon EMR on EKS. In enterprise environments with diverse workloads or varying operational requirements, customers frequently choose a multi-cluster setup due to the following advantages:

  • Better resiliency and no single point of failure – If one cluster fails, other clusters can continue processing critical workloads, maintaining business continuity
  • Better security and isolation – Increased isolation between jobs enhances security and simplifies compliance
  • Better scalability – Distributing workloads across clusters enables horizontal scaling to handle peak demands
  • Performance benefits – Minimizing Kubernetes scheduling delays and network bandwidth contention improves job runtimes
  • Increased flexibility – You can enjoy straightforward experimentation and cost optimization through workload segregation to multiple clusters

However, one of the disadvantages of a multi-cluster setup is that there is no straightforward method to distribute workloads and support effective load balancing across multiple clusters. This post proposes a solution to this challenge by introducing the Batch Processing Gateway (BPG), a centralized gateway that automates job management and routing in multi-cluster environments.

Challenges with multi-cluster environments

In a multi-cluster environment, Spark jobs on Amazon EMR on EKS need to be submitted to different clusters from various clients. This architecture introduces several key challenges:

  • Endpoint management – Clients must maintain and update connections for each target cluster
  • Operational overhead – Managing multiple client connections individually increases the complexity and operational burden
  • Workload distribution – There is no built-in mechanism for job routing across multiple clusters, which impacts configuration, resource allocation, cost transparency, and resilience
  • Resilience and high availability – Without load balancing, the environment lacks fault tolerance and high availability

BPG addresses these challenges by providing a single point of submission for Spark jobs. BPG automates job routing to the appropriate EMR on EKS clusters, providing effective load balancing, simplified endpoint management, and improved resilience. The proposed solution is particularly beneficial for customers with multi-cluster Amazon EMR on EKS setups using the Spark Kubernetes Operator with or without Yunikorn scheduler.

However, although BPG offers significant benefits, it is currently designed to work only with Spark Kubernetes Operator. Additionally, BPG has not been tested with the Volcano scheduler, and the solution is not applicable in environments using native Amazon EMR on EKS APIs.

Solution overview

Martin Fowler describes a gateway as an object that encapsulates access to an external system or resource. In this case, the resource is the EMR on EKS clusters running Spark. A gateway acts as a single point to confront this resource. Any code or connection interacts with the interface of the gateway only. The gateway then translates the incoming API request into the API offered by the resource.

BPG is a gateway specifically designed to provide a seamless interface to Spark on Kubernetes. It’s a REST API service to abstract the underlying Spark on EKS clusters details from users. It runs in its own EKS cluster communicating to Kubernetes API servers of different EKS clusters. Spark users submit an application to BPG through clients, then BPG routes the application to one of the underlying EKS clusters.

The process for submitting Spark jobs using BPG for Amazon EMR on EKS is as follows:

  1. The user submits a job to BPG using a client.
  2. BPG parses the request, translates it into a custom resource definition (CRD), and submits the CRD to an EMR on EKS cluster according to predefined rules.
  3. The Spark Kubernetes Operator interprets the job specification and initiates the job on the cluster.
  4. The Kubernetes scheduler schedules and manages the run of the jobs.

The following figure illustrates the high-level details of BPG. You can read more about BPG in the GitHub README.

Image showing the high-level details of Batch Processing Gateway

The proposed solution involves implementing BPG for multiple underlying EMR on EKS clusters, which effectively resolves the drawbacks discussed earlier. The following diagram illustrates the details of the solution.

Image showing the end to end architecture of of Batch Processing Gateway

Source Code

You can find the code base in the AWS Samples and Batch Processing Gateway GitHub repository.

In the following sections, we walk through the steps to implement the solution.

Prerequisites

Before you deploy this solution, make sure the following prerequisites are in place:

Clone the repositories to your local machine

We assume that all repositories are cloned into the home directory (~/). All relative paths provided are based on this assumption. If you have cloned the repositories to a different location, adjust the paths accordingly.

  1. Clone the BPG on EMR on EKS GitHub repo with the following command:
cd ~/
git clone [email protected]:aws-samples/batch-processing-gateway-on-emr-on-eks.git

The BPG repository is currently under active development. To provide a stable deployment experience consistent with the provided instructions, we have pinned the repository to the stable commit hash aa3e5c8be973bee54ac700ada963667e5913c865.

Before cloning the repository, verify any security updates and adhere to your organization’s security practices.

  1. Clone the BPG GitHub repo with the following command:
git clone [email protected]:apple/batch-processing-gateway.git
cd batch-processing-gateway
git checkout aa3e5c8be973bee54ac700ada963667e5913c865

Create two EMR on EKS clusters

The creation of EMR on EKS clusters is not the primary focus of this post. For comprehensive instructions, refer to Running Spark jobs with the Spark operator. However, for your convenience, we have included the steps for setting up the EMR on EKS virtual clusters named spark-cluster-a-v and spark-cluster-b-v in the GitHub repo. Follow these steps to create the clusters.

After successfully completing the steps, you should have two EMR on EKS virtual clusters named spark-cluster-a-v and spark-cluster-b-v running on the EKS clusters spark-cluster-a and spark-cluster-b, respectively.

To verify the successful creation of the clusters, open the Amazon EMR console and choose Virtual clusters under EMR on EKS in the navigation pane.

Image showing the Amazon EMR on EKS setup

Set up BPG on Amazon EKS

To set up BPG on Amazon EKS, complete the following steps:

  1. Change to the appropriate directory:
cd ~/batch-processing-gateway-on-emr-on-eks/bpg/
  1. Set up the AWS Region:
export AWS_REGION="<AWS_REGION>"
  1. Create a key pair. Make sure you follow your organization’s best practices for key pair management.
aws ec2 create-key-pair \
--region "$AWS_REGION" \
--key-name ekskp \
--key-type ed25519 \
--key-format pem \
--query "KeyMaterial" \
--output text > ekskp.pem
chmod 400 ekskp.pem
ssh-keygen -y -f ekskp.pem > eks_publickey.pem
chmod 400 eks_publickey.pem

Now you’re ready to create the EKS cluster.

By default, eksctl creates an EKS cluster in dedicated virtual private clouds (VPCs). To avoid reaching the default soft limit on the number of VPCs in an account, we use the --vpc-public-subnets parameter to create clusters in an existing VPC. For this post, we use the default VPC for deploying the solution. Modify the following code to deploy the solution in the appropriate VPC in accordance with your organization’s best practices. For official guidance, refer to Create a VPC.

  1. Get the public subnets for your VPC:
export DEFAULT_FOR_AZ_SUBNET=$(aws ec2 describe-subnets --region "$AWS_REGION" --filters "Name=default-for-az,Values=true" --query "Subnets[?AvailabilityZone != 'us-east-1e'].SubnetId" | jq -r '. | map(tostring) | join(",")')
  1. Create the cluster:
eksctl create cluster \
--name bpg-cluster \
--region "$AWS_REGION" \
--vpc-public-subnets "$DEFAULT_FOR_AZ_SUBNET" \
--with-oidc \
--ssh-access \
--ssh-public-key eks_publickey.pem \
--instance-types=m5.xlarge \
--managed
  1. On the Amazon EKS console, choose Clusters in the navigation pane and check for the successful provisioning of the bpg-cluster

Image showing the Amazon EKS based BPG cluster setup

In the next steps, we make the following changes to the existing batch-processing-gateway code base:

For your convenience, we have provided the updated files in the batch-processing-gateway-on-emr-on-eks repository. You can copy these files into the batch-processing-gateway repository.

  1. Replace POM xml file:
cp ~/batch-processing-gateway-on-emr-on-eks/bpg/pom.xml ~/batch-processing-gateway/pom.xml
  1. Replace DAO java file:
cp ~/batch-processing-gateway-on-emr-on-eks/bpg/LogDao.java ~/batch-processing-gateway/src/main/java/com/apple/spark/core/LogDao.java
  1. Replace the Dockerfile:
cp ~/batch-processing-gateway-on-emr-on-eks/bpg/Dockerfile ~/batch-processing-gateway/Dockerfile

Now you’re ready to build your Docker image.

  1. Create a private Amazon Elastic Container Registry (Amazon ECR) repository:
aws ecr create-repository --repository-name bpg --region "$AWS_REGION"
  1. Get the AWS account ID:
export AWS_ACCOUNT_ID=$(aws sts get-caller-identity --query "Account" --output text)

  1. Authenticate Docker to your ECR registry:
aws ecr get-login-password --region "$AWS_REGION" | docker login --username AWS --password-stdin "$AWS_ACCOUNT_ID".dkr.ecr."$AWS_REGION".amazonaws.com
  1. Build your Docker image:
cd ~/batch-processing-gateway/
docker build \
--platform linux/amd64 \
--build-arg VERSION="1.0.0" \
--build-arg BUILD_TIME=$(date -u +"%Y-%m-%dT%H:%M:%SZ") \
--build-arg GIT_COMMIT=$(git rev-parse HEAD) \
--progress=plain \
--no-cache \
-t bpg:1.0.0 .
  1. Tag your image:
docker tag bpg:1.0.0 "$AWS_ACCOUNT_ID".dkr.ecr."$AWS_REGION".amazonaws.com/bpg:1.0.0
  1. Push the image to your ECR repository:
docker push "$AWS_ACCOUNT_ID".dkr.ecr."$AWS_REGION".amazonaws.com/bpg:1.0.0

The ImagePullPolicy in the batch-processing-gateway GitHub repo is set to IfNotPresent. Update the image tag in case you need to update the image.

  1. To verify the successful creation and upload of the Docker image, open the Amazon ECR console, choose Repositories under Private registry in the navigation pane, and locate the bpg repository:

Image showing the Amazon ECR setup

Set up an Amazon Aurora MySQL database

Complete the following steps to set up an Amazon Aurora MySQL-Compatible Edition database:

  1. List all default subnets for the given Availability Zone in a specific format:
DEFAULT_FOR_AZ_SUBNET_RFMT=$(aws ec2 describe-subnets --region "$AWS_REGION" --filters "Name=default-for-az,Values=true" --query "Subnets[*].SubnetId" | jq -c '.')
  1. Create a subnet group. Refer to create-db-subnet-group for more details.
aws rds create-db-subnet-group \
--db-subnet-group-name bpg-rds-subnetgroup \
--db-subnet-group-description "BPG Subnet Group for RDS" \
--subnet-ids "$DEFAULT_FOR_AZ_SUBNET_RFMT" \
--region "$AWS_REGION"
  1. List the default VPC:
export DEFAULT_VPC=$(aws ec2 describe-vpcs --region "$AWS_REGION" --filters "Name=isDefault,Values=true" --query "Vpcs[0].VpcId" --output text)
  1. Create a security group:
aws ec2 create-security-group \
--group-name bpg-rds-securitygroup \
--description "BPG Security Group for RDS" \
--vpc-id "$DEFAULT_VPC" \
--region "$AWS_REGION"
  1. List the bpg-rds-securitygroup security group ID:
export BPG_RDS_SG=$(aws ec2 describe-security-groups --filters "Name=group-name,Values=bpg-rds-securitygroup" --query "SecurityGroups[*].GroupId" --output text)
  1. Create the Aurora DB Regional cluster. Refer to create-db-cluster for more details.
aws rds create-db-cluster \
--database-name bpg \
--db-cluster-identifier bpg \
--engine aurora-mysql \
--engine-version 8.0.mysql_aurora.3.06.1 \
--master-username admin \
--manage-master-user-password \
--db-subnet-group-name bpg-rds-subnetgroup \
--vpc-security-group-ids "$BPG_RDS_SG" \
--region "$AWS_REGION"
  1. Create a DB Writer instance in the cluster. Refer to create-db-instance for more details.
aws rds create-db-instance \
--db-instance-identifier bpg \
--db-cluster-identifier bpg \
--db-instance-class db.r5.large \
--engine aurora-mysql \
--region "$AWS_REGION"

  1. To verify the successful creation of the RDS Regional cluster and Writer instance, on the Amazon RDS console, choose Databases in the navigation pane and check for the bpg database.

Image showing the RDS setup

Set up network connectivity

Security groups for EKS clusters are typically associated with the nodes and the control plane (if using managed nodes). In this section, we configure the networking to allow the node security group of the bpg-cluster to communicate with spark-cluster-a, spark-cluster-b, and the bpg Aurora RDS cluster.

  1. Identify the security groups of bpg-cluster, spark-cluster-a, spark-cluster-b, and the bpg Aurora RDS cluster:
# Identify Node Security Group of the bpg-cluster
BPG_CLUSTER_NODEGROUP_SG=$(aws ec2 describe-instances \
--filters Name=tag:eks:cluster-name,Values=bpg-cluster \
--query "Reservations[*].Instances[*].SecurityGroups[?contains(GroupName, 'eks-cluster-sg-bpg-cluster-')].GroupId" \
--region "$AWS_REGION" \
--output text | uniq)

# Identify Cluster security group of spark-cluster-a and spark-cluster-b
SPARK_A_CLUSTER_SG=$(aws eks describe-cluster --name spark-cluster-a --query "cluster.resourcesVpcConfig.clusterSecurityGroupId" --output text)
SPARK_B_CLUSTER_SG=$(aws eks describe-cluster --name spark-cluster-b --query "cluster.resourcesVpcConfig.clusterSecurityGroupId" --output text)

# Identify Cluster security group of bpg Aurora RDS cluster Writer Instance
BPG_RDS_WRITER_SG=$(aws ec2 describe-security-groups --filters "Name=group-name,Values=bpg-rds-securitygroup" --query "SecurityGroups[*].GroupId" --output text)

  1. Allow the node security group of the bpg-cluster to communicate with spark-cluster-a, spark-cluster-b, and the bpg Aurora RDS cluster:
# spark-cluster-a
aws ec2 authorize-security-group-ingress --group-id "$SPARK_A_CLUSTER_SG" --protocol tcp --port 443 --source-group "$BPG_CLUSTER_NODEGROUP_SG"

# spark-cluster-b
aws ec2 authorize-security-group-ingress --group-id "$SPARK_B_CLUSTER_SG" --protocol tcp --port 443 --source-group "$BPG_CLUSTER_NODEGROUP_SG"

# bpg-rds
aws ec2 authorize-security-group-ingress --group-id "$BPG_RDS_WRITER_SG" --protocol tcp --port 3306 --source-group "$BPG_CLUSTER_NODEGROUP_SG"

Deploy BPG

We deploy BPG for weight-based cluster selection. spark-cluster-a-v and spark-cluster-b-v are configured with a queue named dev and weight=50. We expect statistically equal distribution of jobs between the two clusters. For more information, refer to Weight Based Cluster Selection.

  1. Get the bpg-cluster context:
BPG_CLUSTER_CONTEXT=$(kubectl config view --output=json | jq -r '.contexts[] | select(.name | contains("bpg-cluster")) | .name')
kubectl config use-context "$BPG_CLUSTER_CONTEXT"

  1. Create a Kubernetes namespace for BPG:
kubectl create namespace bpg

The helm chart for BPG requires a values.yaml file. This file includes various key-value pairs for each EMR on EKS clusters, EKS cluster, and Aurora cluster. Manually updating the values.yaml file can be cumbersome. To simplify this process, we’ve automated the creation of the values.yaml file.

  1. Run the following script to generate the values.yaml file:
cd ~/batch-processing-gateway-on-emr-on-eks/bpg
chmod 755 create-bpg-values-yaml.sh
./create-bpg-values-yaml.sh
  1. Use the following code to deploy the helm chart. Make sure the tag value in both values.template.yaml and values.yaml matches the Docker image tag specified earlier.
cp ~/batch-processing-gateway/helm/batch-processing-gateway/values.yaml ~/batch-processing-gateway/helm/batch-processing-gateway/values.yaml.$(date +'%Y%m%d%H%M%S') \
&& cp ~/batch-processing-gateway-on-emr-on-eks/bpg/values.yaml ~/batch-processing-gateway/helm/batch-processing-gateway/values.yaml \
&& cd ~/batch-processing-gateway/helm/batch-processing-gateway/

kubectl config use-context "$BPG_CLUSTER_CONTEXT"

helm install batch-processing-gateway . --values values.yaml -n bpg

  1. Verify the deployment by listing the pods and viewing the pod logs:
kubectl get pods --namespace bpg
kubectl logs <BPG-PODNAME> --namespace bpg
  1. Exec into the BPG pod and verify the health check:
kubectl exec -it <BPG-PODNAME> -n bpg -- bash 
curl -u admin:admin localhost:8080/skatev2/healthcheck/status

We get the following output:

{"status":"OK"}

BPG is successfully deployed on the EKS cluster.

Test the solution

To test the solution, you can submit multiple Spark jobs by running the following sample code multiple times. The code submits the SparkPi Spark job to the BPG, which in turn submits the jobs to the EMR on EKS cluster based on the set parameters.

  1. Set the kubectl context to the bpg cluster:
kubectl config get-contexts | awk 'NR==1 || /bpg-cluster/'
kubectl config use-context "<CONTEXT_NAME>"
  1. Identify the bpg pod name:
kubectl get pods --namespace bpg
  1. Exec into the bpg pod:

kubectl exec -it "<BPG-PODNAME>" -n bpg -- bash

  1. Submit multiple Spark jobs using the curl. Run the below curl command to submit jobs to spark-cluster-a and spark-cluster-b:
curl -u user:pass localhost:8080/skatev2/spark -i -X POST \
-H 'Content-Type: application/json' \
-d '{
"applicationName": "SparkPiDemo",
"queue": "dev",
"sparkVersion": "3.5.0",
"mainApplicationFile": "local:///usr/lib/spark/examples/jars/spark-examples.jar",
"mainClass":"org.apache.spark.examples.SparkPi",
"driver": {
"cores": 1,
"memory": "2g",
"serviceAccount": "emr-containers-sa-spark",
"labels":{
"version": "3.5.0"
}
},
"executor": {
"instances": 1,
"cores": 1,
"memory": "2g",
"labels":{
"version": "3.5.0"
}
}
}'

After each submission, BPG will inform you of the cluster to which the job was submitted. For example:

HTTP/1.1 200 OK
Date: Sat, 10 Aug 2024 16:17:15 GMT
Content-Type: application/json
Content-Length: 67
{"submissionId":"spark-cluster-a-f72a7ddcfde14f4390194d4027c1e1d6"}
{"submissionId":"spark-cluster-a-d1b359190c7646fa9d704122fbf8c580"}
{"submissionId":"spark-cluster-b-7b61d5d512bb4adeb1dd8a9977d605df"}
  1. Verify that the jobs are running in the EMR cluster spark-cluster-a and spark-cluster-b:
kubectl config get-contexts | awk 'NR==1 || /spark-cluster-(a|b)/'
kubectl get pods -n spark-operator --context "<CONTEXT_NAME>"

You can view the Spark Driver logs to find the value of Pi as shown below:

kubectl logs <SPARK-DRIVER-POD-NAME> --namespace spark-operator --context "<CONTEXT_NAME>"

After successful completion of the job, you should be able to see the below message in the logs:

Pi is roughly 3.1452757263786317

We have successfully tested the weight-based routing of Spark jobs across multiple clusters.

Clean up

To clean up your resources, complete the following steps:

  1. Delete the EMR on EKS virtual cluster:
VIRTUAL_CLUSTER_ID=$(aws emr-containers list-virtual-clusters --region="$AWS_REGION" --query "virtualClusters[?name=='spark-cluster-a-v' && state=='RUNNING'].id" --output text)
aws emr-containers delete-virtual-cluster --region="$AWS_REGION" --id "$VIRTUAL_CLUSTER_ID"
VIRTUAL_CLUSTER_ID=$(aws emr-containers list-virtual-clusters --region="$AWS_REGION" --query "virtualClusters[?name=='spark-cluster-b-v' && state=='RUNNING'].id" --output text)
aws emr-containers delete-virtual-cluster --region="$AWS_REGION" --id "$VIRTUAL_CLUSTER_ID"

  1. Delete the AWS Identity and Access Management (IAM) role:
aws iam delete-role-policy --role-name sparkjobrole --policy-name EMR-Spark-Job-Execution
aws iam delete-role --role-name sparkjobrole

  1. Delete the RDS DB instance and DB cluster:
aws rds delete-db-instance \
--db-instance-identifier bpg \
--skip-final-snapshot

aws rds delete-db-cluster \
--db-cluster-identifier bpg \
--skip-final-snapshot

  1. Delete the bpg-rds-securitygroup security group and bpg-rds-subnetgroup subnet group:
BPG_SG=$(aws ec2 describe-security-groups --filters "Name=group-name,Values=bpg-rds-securitygroup" --query "SecurityGroups[*].GroupId" --output text)
aws ec2 delete-security-group --group-id "$BPG_SG"
aws rds delete-db-subnet-group --db-subnet-group-name bpg-rds-subnetgroup

  1. Delete the EKS clusters:
eksctl delete cluster --region="$AWS_REGION" --name=bpg-cluster
eksctl delete cluster --region="$AWS_REGION" --name=spark-cluster-a
eksctl delete cluster --region="$AWS_REGION" --name=spark-cluster-b

  1. Delete bpg ECR repository:
aws ecr delete-repository --repository-name bpg --region="$AWS_REGION" --force

  1. Delete the key pairs:
aws ec2 delete-key-pair --key-name ekskp
aws ec2 delete-key-pair --key-name emrkp

Conclusion

In this post, we explored the challenges associated with managing workloads on EMR on EKS cluster and demonstrated the advantages of adopting a multi-cluster deployment pattern. We introduced Batch Processing Gateway (BPG) as a solution to these challenges, showcasing how it simplifies job management, enhances resilience, and improves horizontal scalability in multi-cluster environments. By implementing BPG, we illustrated the practical application of the gateway architecture pattern for submitting Spark jobs on Amazon EMR on EKS. This post provides a comprehensive understanding of the problem, the benefits of the gateway architecture, and the steps to implement BPG effectively.

We encourage you to evaluate your existing Spark on Amazon EMR on EKS implementation and consider adopting this solution. It allows users to submit, examine, and delete Spark applications on Kubernetes with intuitive API calls, without needing to worry about the underlying complexities.

For this post, we focused on the implementation details of the BPG. As a next step, you can explore integrating BPG with clients such as Apache Airflow, Amazon Managed Workflows for Apache Airflow (Amazon MWAA), or Jupyter notebooks. BPG works well with the Apache Yunikorn scheduler. You can also explore integrating BPG to use Yunikorn queues for job submission.


About the Authors

Image of Author: Umair NawazUmair Nawaz is a Senior DevOps Architect at Amazon Web Services. He works on building secure architectures and advises enterprises on agile software delivery. He is motivated to solve problems strategically by utilizing modern technologies.

Image of Author: Ravikiran RaoRavikiran Rao is a Data Architect at Amazon Web Services and is passionate about solving complex data challenges for various customers. Outside of work, he is a theater enthusiast and amateur tennis player.

Image of Author: Sri PotluriSri Potluri is a Cloud Infrastructure Architect at Amazon Web Services. He is passionate about solving complex problems and delivering well-structured solutions for diverse customers. His expertise spans across a range of cloud technologies, ensuring scalable and reliable infrastructure tailored to each project’s unique challenges.

Image of Author: Suvojit DasguptaSuvojit Dasgupta is a Principal Data Architect at Amazon Web Services. He leads a team of skilled engineers in designing and building scalable data solutions for AWS customers. He specializes in developing and implementing innovative data architectures to address complex business challenges.

Reduce risks of user sign-up fraud and SMS pumping with Amazon Cognito user pools

Post Syndicated from Edward Sun original https://aws.amazon.com/blogs/security/reduce-risks-of-user-sign-up-fraud-and-sms-pumping-with-amazon-cognito-user-pools/

If you have a customer facing application, you might want to enable self-service sign-up, which allows potential customers on the internet to create an account and gain access to your applications. While it’s necessary to allow valid users to sign up to your application, self-service options can open the door to unintended use or sign-ups. Bad actors might leverage the user sign-up process for unintended purposes, launching large-scale distributed denial of service (DDoS) attacks to disrupt access for legitimate users or committing a form of telecommunications fraud known as SMS pumping. SMS pumping is when bad actors purchase a block of high-rate phone numbers from a telecom provider and then coerces unsuspecting services into sending SMS messages to those numbers.

Amazon Cognito is a managed OpenID Connect (OIDC) identity provider (IdP) that you can use to add self-service sign-up, sign-in, and control access features to your web and mobile applications. AWS customers who use Cognito might encounter SMS pumping if SMS functions are enabled to send SMS messages, for example, perform user phone number verification during the registration process, to facilitate SMS multi-factor authentication (MFA) flows, or to support account recovery using SMS. In this blog post, we explore how SMS pumping may be perpetrated and options to reduce risks, including blocking unexpected user registration, detecting anomalies, and responding to risk events with your Cognito user pool.

Cognito user sign-up process

After a user has signed up in your application with an Amazon Cognito user pool, their account is placed in the Registered (unconfirmed) state in your user pool and the user won’t be able to sign in yet. You can use the Cognito-assisted verification and confirmation process to verify user-provided attributes (such as email or phone number) and then confirm the user’s status. This verified attribute is also used for MFA and account recovery purposes. If you choose to verify the user’s phone number, Cognito sends SMS messages with a one-time password (OTP). After a user has provided the correct OTP, their email or phone number is marked as verified and the user can sign in to your application.

Figure 1: Amazon Cognito sign-up process

Figure 1: Amazon Cognito sign-up process

If the sign-up process isn’t protected, bad actors can create scripts or deploy bots to sign up a large number of accounts, resulting in a significant volume of SMS messages sent in a short period of time. We dive deep into prevention, detection, and remediation mechanisms and strategies that you can apply to help protect against SMS pumping based on your use case.

Protect the sign-up flow

In this section, we review several prevention strategies to help protect against SMS sign-up frauds and help reduce the amount of SMS messages sent to bad actors.

Implement bot mitigation

Implementing bot mitigation techniques, such as CAPTCHA, can be very effective in preventing simple bots from pumping user creation flows. You can integrate a CAPTCHA framework on your application’s frontend and validate that the client initiating the sign-up request is operated by a human user. If the user has passed the verification, you then pass the CAPTCHA user response token in ClientMetadata together with user attributes to an Amazon Cognito SignUp API call. As part of the sign-up process, Cognito invokes an AWS Lambda function called pre sign-up Lambda trigger, which you can use to reject sign-up requests if there isn’t a valid CAPTCHA token presented. This will slow down bots and help reduce unintended account creation in your Cognito user pool.

Validate phone number before user sign-up

Another layer of mitigation is to identify the actor’s phone number early in your application’s sign-up process. You can validate the user provided phone number in the backend to catch incorrectly formatted phone numbers and add logic to help filter out unwanted phone numbers prior to sending text messages. Amazon Pinpoint offers a Phone Number Validate feature that can help you determine if a user-provided phone number is valid, determine phone number type (such as mobile, landline, or VoIP), and identify the country and service provider the phone number is associated with. The returned phone number metadata can be used to decide whether the user will continue the sign-up process and send an SMS message to that user. Note that there’s an additional charge for using the phone number validation service. For more information, see Amazon Pinpoint pricing.

To build this validation check into the Amazon Cognito sign-up process, you can customize the pre sign-up Lambda trigger, which Cognito uses to invoke your code before allowing users to sign-up and sending out an SMS OTP. The Lambda trigger invokes the Amazon Pinpoint phone number validate API, and based on the validation response, you can build a custom pattern that fits your application to continue or reject the user sign-up. For example, you can reject user sign-ups with VoIP numbers or reject users who provide a phone number that’s associated with countries that you don’t operate in, or even reject certain cellular service providers. After you reject a user sign-up using the Lambda trigger, Cognito will deny the user sign-up request and will not invoke user confirmation flow nor send out an SMS message.

Example validation command using AWS CLI

aws pinpoint phone-number-validate --number-validate-request PhoneNumber=+155501001234

When you send a request to the Amazon Pinpoint phone number validation service, it returns the following metadata about the phone number. The following example represents a valid mobile phone number data set:

{
    "NumberValidateResponse": {
        "Carrier": "ExampleCorp Mobile",
        "City": "Seattle",
        "CleansedPhoneNumberE164": "+155501001234",
        "CleansedPhoneNumberNational": "55501001234",
        "Country": "United States",
        "CountryCodeIso2": "US",
        "CountryCodeNumeric": "1",
        "OriginalPhoneNumber": "+155501001234",
        "PhoneType": "MOBILE",
        "PhoneTypeCode": 0,
        "Timezone": "America/Seattle",
        "ZipCode": "98109"
    }
}

Note that PhoneType includes type MOBILE, LANDLINE, VOIP, INVALID, or OTHER. INVALID phone numbers don’t include information about the carrier or location associated with the phone number and are unlikely to belong to actual recipients. This helps you decide when to reject user sign-ups and reduces SMS messages to undesired phone numbers. You can see details about other responses in the Amazon Pinpoint developer guide.

Example pre sign-up Lambda function to block user sign-up except with a valid MOBILE number

The following pre sign-up Lambda function example invokes the Amazon Pinpoint phone number validation service and rejects user sign-ups unless the validation service returns a valid mobile phone number.

import { PinpointClient, PhoneNumberValidateCommand } from "@aws-sdk/client-pinpoint"; // ES Modules import

const validatePhoneNumber = async (phoneNumber) => {
  const pinpoint = new PinpointClient();
  const input = { // PhoneNumberValidateRequest
    NumberValidateRequest: { // NumberValidateRequest
      PhoneNumber: phoneNumber,
    },
  };
  const command = new PhoneNumberValidateCommand(input);
  const response = await pinpoint.send(command);

  return response;
};

const handler = async (event, context, callback) => {

  const phoneNumber = event.request.userAttributes.phone_number;
  const validationResponse = await validatePhoneNumber(phoneNumber);

  if (validationResponse.NumberValidateResponse.PhoneType != "MOBILE") {
    var error = new Error("Cannot register users without a mobile number");
    // Return error to Amazon Cognito
    callback(error, event);
  }
  // Return to Amazon Cognito
  callback(null, event);
};

export { handler };

Use a custom user-initiated confirmation flow or alternative OTP delivery method

In your user pool configurations, you can opt out of using Amazon Cognito-assisted verification and confirmation to send SMS messages to confirm users. Instead, you can build a custom reverse OTP flow to ask your users to initiate the user confirmation process. For example, instead of automatically sending SMS messages to a user when they sign up, your application can display an OTP and direct the user to initiate the SMS conversation by texting the OTP to your service number. After your application has received the SMS message and confirmed the correct OTP is provided, invoke a service such as a Lambda function to call the AdminConfirmSignUp administrative API operation to confirm user, then call AdminUpdateUserAttributes to set the phone_number_verified attribute as true to indicate that the user phone number is verified.

You can also choose to deliver an OTP using other methods, such as email, especially if your application doesn’t require the user’s phone number. During the user sign-up process, you can configure a custom SMS sender Lambda trigger in Amazon Cognito to send a user verification code through email or another method. Additionally, you can use the Cognito email MFA feature to send MFA codes through email.

Detect SMS pumping

When you’re considering the various prevention options, it’s important to set up detection mechanisms to identify SMS pumping as they arise. In this section, we show you how to use AWS CloudTrail and Amazon CloudWatch to monitor your Amazon Cognito user pool and detect anomalies that could lead to SMS pumping. Note that building detection mechanism based on anomalies requires knowing your average or baseline traffic and the difference in metrics that represent regular activity and metrics that can indicate unauthorized or unintended activity.

Service quotas dashboard and CloudWatch alarms

Bad actors may attempt to leverage either the sign-up confirmation or the reset password functionality of Amazon Cognito. As shown previously in Figure 1, when a new user signs up to your Cognito user pool, the SignUp API operation is invoked. When the user provides the OTP confirmation code, the ConfirmSignUp API operation is invoked. The call rate of both APIs is tracked collectively under Rate of UserCreation requests under Amazon Cognito service in the service quotas dashboard.

You can set up Amazon CloudWatch alarms to monitor and issue notifications when you’re close to a quota value threshold. These alarms could be an early indication of a sudden usage increase, and you can use them to triage potential incidents.

Additionally, when your services are sending SMS messages, those transactions count towards the Amazon Simple Notification Service (Amazon SNS) service quota. You should set up alarms to monitor the Transactional SMS Message Delivery Rate per Second quota and the SMS Message Spending in USD quota.

CloudTrail event history

When bad actors plan SMS pumping, they are likely attempting to trick you to send as many SMS messages as possible rather than completing the user confirmation process. Under the context of a user sign-up event, you might notice in the CloudTrail event history that there are more SignUp and ResendConfirmationCode events—which send out SMS messages—than ConfirmSignUp operations; indicating a user has initiated but not completed the sign-up process. You can use Amazon Athena or CloudWatch Logs Insights to search and analyze your Amazon Cognito CloudTrail events and identify if there’s a significant reduction in finishing the user sign-up process.

Figure 2: SignUp API logged in CloudTrail event history

Figure 2: SignUp API logged in CloudTrail event history

Similarly, you can apply this observability towards the user password reset flow by analyzing the ForgotPassword API and ConfirmForgotPassword API operations for deviations.

Note that the slight deviations in user completion flow in the CloudTrail event history alone might not be an indication of unauthorized activity, however a substantial deviation above the regular baseline might be a signal of unintended use.

Monitor excessive billing

Another opportunity for detecting and identifying unauthorized Amazon Cognito activity is by using AWS Cost Explorer. You can use this interface to visualize, understand, and manage your AWS costs and usage over time, which might assist by highlighting the source of excessive billing in your AWS account. Be aware that charges in your account can take up to 24 hours to be displayed, so while this method can help provide some assistance in identifying SMS pumping activity, it should only be used as a supplement to other detection methods.

To use Cost Explorer:

  1. Open the AWS Management Console, and go to Billing and Cost Management.
  2. In the navigation pane, under Cost Analysis, choose Cost Explorer.
  3. In the Cost and Usage Report, under Report Parameters, select Date Range to include the start and end date of the time period that you want to apply a filter to. In Figure 3 that follows, we use an example date range between 2024-07-03 and 2024-07-17.
  4. In the same Report Parameter area, under Filters, for Service, select SNS (Simple Notification Service). Because Amazon Cognito uses Amazon SNS for delivery of SMS messages, filtering on SNS can help you identify excessive billing.

Figure 3: Reviewing billing charges by service

Figure 3: Reviewing billing charges by service

Apply AWS WAF rules as mitigation approaches

It’s recommended that you apply AWS WAF with your Amazon Cognito user pool to protect against common threats. In this section, we show you a few advanced options using AWS WAF rules to block or throttle specific bad actor’s traffic when you have observed irregular sign-up attempts and suspect they were part of fraudulent activities.

Target a specific bad actor’s IP address

When building AWS WAF remediation strategies, you can start by building an IP deny list to block traffic from known malicious IP addresses. This method is straightforward and can be highly effective in preventing unwanted access. For detailed instructions on how to set up an IP deny list, see Creating an IP set.

Target a specific phone number area code regex pattern

In an SMS pumping scheme, bad actors often purchase blocks of cell phone numbers from a wireless service provider and use phone numbers with the same area code. If you observe a pattern and identify that these attempts use the same area code, you can apply an AWS WAF rule to block that specific traffic.

To configure an AWS WAF web ACL to block using an area code regex pattern:

  1. Open the AWS WAF console.
  2. In the navigation pane, under AWS WAF, choose WAF ACLs.
  3. Choose Create web ACL. Under Web ACL details, select Regional resources, and select the AWS Region as your Amazon Cognito user pool. Under Associated AWS resources, select Add AWS resources, and choose your Cognito user pool. Choose Next.
  4. On the Add rules and rule groups page, choose Add rules, Add my own rules and rule groups, and Rule builder.
  5. Create a rule in Rule builder.
    1. For If a request, select matches the statement.
    2. For Inspect, select Body.
    3. For Match type, select Matches regular expression.
    4. For Regular expression, enter a match for the observed pattern. For example, the regular expression ^303|^\+1303|^001303 will match requests that include the digits 303, +1303, or 001303 at the beginning of any string in the body of a request:

    Figure 4: Creating a web ACL

    Figure 4: Creating a web ACL

  6. Under Action, choose Block. Then, choose Add rule.
  7. Continue with Set rule priority and Configure metrics, then choose Create web ACL.

Be aware that this method will block all user sign-up requests that contain phone numbers matching the regex pattern for the target area code and could prevent legitimate users whose numbers match the defined pattern from signing up. For example, the rule above will apply to all users with phone numbers starting with 303, +1303, or 001303. You should consider implementing this method as an as-needed solution to address an ongoing SMS pumping attack.

Target a specific bad actor’s client fingerprint

Another method is to examine an actor’s TLS traffic. If your application UI is hosted using Amazon CloudFront or Application Load Balancer (ALB), you can build AWS WAF rules to match the client’s JA3 fingerprint. The JA3 fingerprint is a 32-character MD5 hash derived from the TLS three-way handshake when the client sends a ClientHello packet to the server. It serves as a unique identifier for the client’s TLS configuration because various attributes such as TLS version, cipher suites, and extensions are derived to calculate the fingerprint, allowing for the unique detection of clients even when the source IP and other commonly used identification information might have changed.

Fraudulent activities, such as SMS pumping, are typically carried out using automated tools and scripts. These tools often have a consistent SSL/TLS handshake pattern, resulting in a unique JA3 fingerprint. By configuring an AWS WAF web ACL rule to match the JA3 fingerprint associated with this traffic, you can identify clients with a high degree of accuracy, even if they change other attributes, such as IP addresses.

AWS WAF has introduced support for JA3 fingerprint matching, which you can use to identify and differentiate clients based on the way they initiate TLS connections, enabling you to inspect incoming requests for their JA3 fingerprints. You can build the remediation strategy by first evaluating AWS WAF logs to extract JA3 fingerprints for potential malicious hosts, then proceed with creating rules to block requests where the fingerprint matches the malicious JA3 fingerprint associated with previous attacks.

To configure an AWS WAF web ACL to block using JA3 fingerprint matching for CloudFront resources:

  1. Open the AWS WAF console.
  2. In the navigation pane, under AWS WAF, choose WAF ACLs.
  3. Choose Create web ACL. Under Web ACL details, select Amazon CloudFront distributions. Under Associated AWS resources, select Add AWS resources, and select your CloudFront distribution. Choose Next.
  4. On the Add rules and rule groups page, choose Add rules, Add my own rules and rule groups, and Rule builder.
  5. In Rule builder:
    1. For If a request, select matches the statement.
    2. For Inspect, select JA3 fingerprint.
    3. For Match type, keep Exactly matches string.
    4. For String to match, enter the JA3 fingerprint that you want to block.
    5. For Text transformation, choose None.
    6. For Fallback for missing JA3 fingerprint, select a fallback match status for cases where no JA3 fingerprint is detected. We recommend choosing No match to prevent unintended traffic blocking.
    7. If you need to block multiple JA3 fingerprints, include each one in the rule and for If a request select matches at least one of the statements (OR).

      Figure 5: Creating an AWS WAF statement for a JA3 fingerprint

      Figure 5: Creating an AWS WAF statement for a JA3 fingerprint

    8. Under Action, select Block, and choose Add rule. You can choose other actions such as COUNT or CAPTCHA that suit your use case.
  6. Continue with Set rule priority and Configure metrics, then choose Create web ACL.

Note that JA3 fingerprints can change over time due to the randomization of TLS ClientHello messages by modern browsers. It’s important to dynamically update your web ACL rules or manually review logs to update the JA3 fingerprint search string in your match rule when applicable.

AWS WAF remediation considerations

These AWS WAF remediation approaches help to block potential threats by providing mechanisms to filter out malicious traffic. It’s essential to continually review the effectiveness of these rules to minimize the risk of blocking legitimate sources and make dynamic adjustments to the rules when you detect new bad actors and patterns.

Summary

In this blog post, we introduced mechanisms that you can use to detect and protect your Amazon Cognito user pool against unintended user sign-up and SMS pumping. By implementing these strategies, you can enhance the security of your web and mobile applications and help to safeguard your services from potential abuse and financial loss. We suggest that you apply a combination of these prevention, detection, and mitigation approaches to protect your Cognito user pools.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
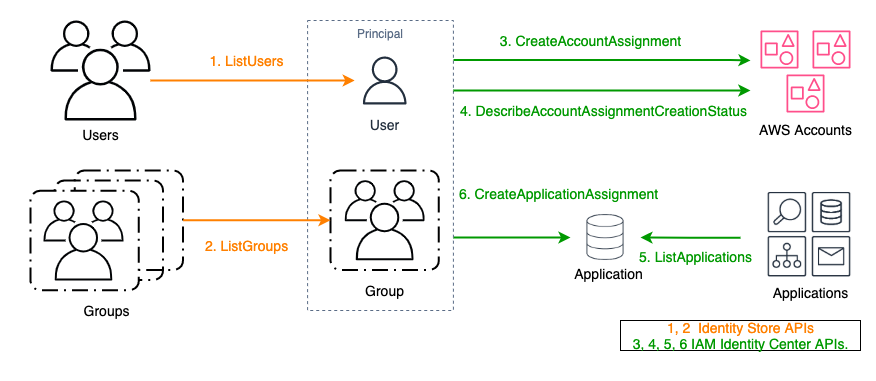
Edward Sun
Edward Sun

Edward is a Security Specialist Solutions Architect focused on identity and access management. He loves helping customers throughout their cloud transformation journey with architecture design, security best practices, migration, and cost optimizations. Outside of work, Edward enjoys hiking, golfing, and cheering for his alma mater, the Georgia Bulldogs.
Steve de Vera
Steve de Vera

Steve is a manager in the AWS Customer Incident Response Team (CIRT). He is passionate about American-style BBQ and is a certified competition BBQ judge. He has a dog named Brisket.
Tony Suarez
Tony Suarez

Tony Suarez is a San Diego, CA based Solutions Architect with over 15 years of experience in IT operations. As a member of the AWS VMware technical field community, Tony enjoys helping customers solve challenging problems in innovative ways. Enabling customers to efficiently manage, automate, and orchestrate large-scale hybrid infrastructure projects is Tony’s passion.

Developer guidance on how to do local testing with Amazon MSK Serverless

Post Syndicated from Simon Peyer original https://aws.amazon.com/blogs/big-data/developer-guidance-on-how-to-do-local-testing-with-amazon-msk-serverless/

Amazon Managed Streaming for Apache Kafka (Amazon MSK) is a fully managed service that makes it easy to build and run Kafka clusters on Amazon Web Services (AWS). When working with Amazon MSK, developers are interested in accessing the service locally. This allows developers to test their application with a Kafka cluster that has the same configuration as production and provides an identical infrastructure to the actual environment without needing to run Kafka locally.

An Amazon MSK Serverless private DNS endpoint is only accessible from Amazon Virtual Private Cloud (Amazon VPC) connections that have been configured to connect. It isn’t directly resolvable from your local development environment. One option is to use AWS Direct Connect or AWS VPN to be able to Connect to Amazon MSK Serverless from your on-premises network. However, building such a solution may incur cost and complexity, and it needs to be set up by a platform team.

This post presents a practical approach to accessing your Amazon MSK environment for development purposes through a bastion host using a Secure Shell (SSH) tunnel (a commonly used secure connection method). Whether you’re working with Amazon MSK Serverless, where public access is unavailable, or with provisioned MSK clusters that are intentionally kept private, this post guides you through the steps to establish a secure connection and seamlessly integrate your local development environment with your MSK resources.

Solution overview

The solution allows you to directly connect to the Amazon MSK Serverless service from your local development environment without using Direct Connect or a VPN. The service is accessed with the bootstrap server DNS endpoint boot-<<xxxxxx>>.c<<x>>.kafka-serverless.<<region-name>>.amazonaws.com on port 9098, then routed through an SSH tunnel to a bastion host, which connects to the MSK Serverless cluster. In the next step, let’s explore how to set up this connection.

The flow of the solution is as follows:

  1. The Kafka client sends a request to connect to the bootstrap server
  2. The DNS query for your MSK Serverless endpoint is routed to a locally configured DNS server
  3. The locally configured DNS server routes the DNS query to localhost.
  4. The SSH tunnel forwards all the traffic on port 9098 from the localhost to the MSK Serverless server through the Amazon Elastic Compute Cloud (Amazon EC2) bastion host.

The following image shows the architecture diagram.

Architecture Diagram for accessing Serverless MSK from local

Prerequisites

Before deploying the solution, you need to have the following resources deployed in your account:

  1. An MSK Serverless cluster configured with AWS Identity and Access Management (IAM) authentication.
  2. A bastion host instance with network access to the MSK Serverless cluster and SSH public key authentication.
  3. AWS CLI configured with an IAM user and able to read and create topics on Amazon MSK. Use the IAM policy from Step 2: Create an IAM role in the Getting started using MSK Serverless clusters
  4. For Windows users, install Linux on Windows with Windows Subsystem for Linux 2 (WSL 2) using Ubuntu 24.04. For guidance, refer to How to install Linux on Windows with WSL.

This guide assumes an MSK Serverless deployment in us-east-1, but it can be used in every AWS Region where MSK Serverless is available. Furthermore, we are using OS X as operating system. In the following steps replace msk-endpoint-url with your MSK Serverless endpoint URL with IAM authentication. The MSK endpoint URL has a format like boot-<<xxxxxx>>.c<<x>>.kafka-serverless.<<region-name>>.amazonaws.com.

Solution walkthrough

To access your Amazon MSK environment for development purposes, use the following walkthrough.

Configure local DNS server OSX

Install Dnsmasq as a local DNS server and configure the resolver to resolve the Amazon MSK. The solution uses Dnsmasq because it can compare DNS requests against a database of patterns and use these to determine the correct response. This functionality can match any request that ends in kafka-serverless.us-east-1.amazonaws.com and send 127.0.0.1 in response. Follow these steps to install Dnsmasq:

  1. Update brew and install Dnsmasq using brew
    brew up
    brew install dnsmasq

  2. Start the Dnsmasq service
    sudo brew services start dnsmasq

  3. Reroute all traffic for Serverless MSK (kafka-serverless.us-east-1.amazonaws.com) to 127.0.0.1
    echo address=/kafka-serverless.us-east-1.amazonaws.com/127.0.0.1 >> $(brew --prefix)/etc/dnsmasq.conf

  4. Reload Dnsmasq configuration and clear cache
    sudo launchctl unload /Library/LaunchDaemons/homebrew.mxcl.dnsmasq.plist
    sudo launchctl load /Library/LaunchDaemons/homebrew.mxcl.dnsmasq.plist
    dscacheutil -flushcache

Configure OS X resolver

Now that you have a working DNS server, you can configure your operating system to use it. Configure the server to send only .kafka-serverless.us-east-1.amazonaws.com queries to Dnsmasq. Most operating systems that are similar to UNIX have a configuration file called /etc/resolv.conf that controls the way DNS queries are performed, including the default server to use for DNS queries. Use the following steps to configure the OS X resolver:

  1. OS X also allows you to configure additional resolvers by creating configuration files in the /etc/resolver/ This directory probably won’t exist on your system, so your first step should be to create it:
    sudo mkdir -p /etc/resolver

  2. Create a new file with the same name as your new top-level domain (kafka-serverless.us-east-1.amazonaws.com) in the /etc/resolver/ directory and add 127.0.0.1 as a nameserver to it by entering the following command.
    sudo tee /etc/resolver/kafka-serverless.us-east-1.amazonaws.com >/dev/null <<EOF
    nameserver 127.0.0.1
    EOF

Configure local DNS server Windows

In Windows Subsystem for Linux, first install Dnsmasq, then configure the resolver to resolve the Amazon MSK and finally add localhost as the first nameserver.

  1. Update apt and install Dnsmasq using apt. Install the telnet utility for later tests:
    sudo apt update
    sudo apt install dnsmasq
    sudo apt install telnet

  2. Reroute all traffic for Serverless MSK (kafka-serverless.us-east-1.amazonaws.com) to 127.0.0.1.
    echo "address=/kafka-serverless.us-east-1.amazonaws.com/127.0.0.1" | sudo tee -a /etc/dnsmasq.conf

  3. Reload Dnsmasq configuration and clear cache.
    sudo /etc/init.d/dnsmasq restart

  4. Open /etc/resolv.conf and add the following code in the first line.
    nameserver 127.0.0.1

    The output should look like the following code.

    #Some comments
    nameserver 127.0.0.1
    nameserver <<your_nameservers>>
    ..

Create SSH tunnel

The next step is to create the SSH tunnel, which will allow any connections made to localhost:9098 on your local machine to be forwarded over the SSH tunnel to the target Kafka broker. Use the following steps to create the SSH tunnel:

  1. Replace bastion-host-dns-endpoint with the public DNS endpoint of the bastion host, which comes in the style of <<xyz>>.compute-1.amazonaws.com, and replace ec2-key-pair.pem with the key pair of the bastion host. Then create the SSH tunnel by entering the following command.
    ssh -i "~/<<ec2-key-pair.pem>>" ec2-user@<<bastion-host-dns-endpoint>> -L 127.0.0.1:9098:<<msk-endpoint-url>>:9098

  2. Leave the SSH tunnel running and open a new terminal window.
  3. Test the connection to the Amazon MSK server by entering the following command.
    telnet <<msk-endpoint-url>> 9098

    The output should look like the following example.

    Trying 127.0.0.1...
    Connected to boot-<<xxxxxxxx>>.c<<x>>.kafka-serverless.us-east-1.amazonaws.com.
    Escape character is '^]'.

Testing

Now configure the Kafka client to use IAM Authentication and then test the setup. You find the latest Kafka installation at the Apache Kafka Download site. Then unzip and copy the content of the Dafka folder into ~/kafka.

  1. Download the IAM authentication and unpack it
    cd ~/kafka/libs
    wget https://github.com/aws/aws-msk-iam-auth/releases/download/v2.2.0/aws-msk-iam-auth-2.2.0-all.jar
    cd ~

  2. Configure Kafka properties to use IAM as the authentication mechanism
    cat <<EOF > ~/kafka/config/client-config.properties
    
    # Sets up TLS for encryption and SASL for authN.
    
    security.protocol = SASL_SSL
    
    # Identifies the SASL mechanism to use.
    
    sasl.mechanism = AWS_MSK_IAM
    
    # Binds SASL client implementation.
    
    sasl.jaas.config = software.amazon.msk.auth.iam.IAMLoginModule required;
    
    
    # Encapsulates constructing a SigV4 signature based on extracted credentials.
    
    # The SASL client bound by "sasl.jaas.config" invokes this class.
    
    sasl.client.callback.handler.class = software.amazon.msk.auth.iam.IAMClientCallbackHandler
    
    EOF

  3. Enter the following command in ~/kafka/bin to create an example topic. Make sure that the SSH tunnel created in the previous section is still open and running.
    ./kafka-topics.sh --bootstrap-server <<msk-endpoint-url>>:9098 --command-config ~/kafka/config/client-config.properties --create --topic ExampleTopic --partitions 10 --replication-factor 3 --config retention.ms=3600000

Cleanup

To remove the solution, complete the following steps for Mac users:

  1. Delete the file /etc/resolver/kafka-serverless.us-east-1.amazonaws.com
  2. Delete the entry address=/kafka-serverless.us-east-1.amazonaws.com/127.0.0.1 in the file $(brew --prefix)/etc/dnsmasq.conf
  3. Stop the Dnsmasq service sudo brew services stop dnsmasq
  4. Remove the Dnsmasq service sudo brew uninstall dnsmasq

To remove the solution, complete the following steps for WSL users:

  1. Delete the file /etc/dnsmasq.conf
  2. Delete the entry nameserver 127.0.0.1 in the file /etc/resolv.conf
  3. Remove the Dnsmasq service sudo apt remove dnsmasq
  4. Remove the telnet utility sudo apt remove telnet

Conclusion

In this post, I presented you with guidance on how developers can connect to Amazon MSK Serverless from local environments. The connection is done using an Amazon MSK endpoint through an SSH tunnel and a bastion host. This enables developers to experiment and test locally, without needing to setup a separate Kafka cluster.


About the Author

Simon Peyer is a Solutions Architect at Amazon Web Services (AWS) based in Switzerland. He is a practical doer and passionate about connecting technology and people using AWS Cloud services. A special focus for him is data streaming and automations. Besides work, Simon enjoys his family, the outdoors, and hiking in the mountains.

Integrate sparse and dense vectors to enhance knowledge retrieval in RAG using Amazon OpenSearch Service

Post Syndicated from Yuanbo Li original https://aws.amazon.com/blogs/big-data/integrate-sparse-and-dense-vectors-to-enhance-knowledge-retrieval-in-rag-using-amazon-opensearch-service/

In the context of Retrieval-Augmented Generation (RAG), knowledge retrieval plays a crucial role, because the effectiveness of retrieval directly impacts the maximum potential of large language model (LLM) generation.

Currently, in RAG retrieval, the most common approach is to use semantic search based on dense vectors. However, dense embeddings do not perform well in understanding specialized terms or jargon in vertical domains. A more advanced method is to combine traditional inverted-index(BM25) based retrieval, but this approach requires spending a considerable amount of time customizing lexicons, synonym dictionaries, and stop-word dictionaries for optimization.

In this post, instead of using the BM25 algorithm, we introduce sparse vector retrieval. This approach offers improved term expansion while maintaining interpretability. We walk through the steps of integrating sparse and dense vectors for knowledge retrieval using Amazon OpenSearch Service and run some experiments on some public datasets to show its advantages. The full code is available in the github repo aws-samples/opensearch-dense-spase-retrieval.

What’s Sparse vector retrieval

Sparse vector retrieval is a recall method based on an inverted index, with an added step of term expansion. It comes in two modes: document-only and bi-encoder. For more details about these two terms, see Improving document retrieval with sparse semantic encoders.

Simply put, in document-only mode, term expansion is performed only during document ingestion. In bi-encoder mode, term expansion is conducted both during ingestion and at the time of query. Bi-encoder mode improves performance but may cause more latency. The following figure demonstrates its effectiveness.

Neural sparse search in OpenSearch achieves 12.7%(document-only) ~ 20%(bi-encoder) higher NDCG@10, comparable to the TAS-B dense vector model.

With neural sparse search, you don’t need to configure the dictionary yourself. It will automatically expand terms for the user. Additionally, in an OpenSearch index with a small and specialized dataset, while hit terms are generally few, the calculated term frequency may also lead to unreliable term weights. This may lead to significant bias or distortion in BM25 scoring. However, sparse vector retrieval first expands terms, greatly increasing the number of hit terms compared to before. This helps produce more reliable scores.

Although the absolute metrics of the sparse vector model can’t surpass those of the best dense vector models, it possesses unique and advantageous characteristics. For instance, in terms of the NDCG@10 metric, as mentioned in Improving document retrieval with sparse semantic encoders, evaluations on some datasets reveal that its performance could be better than state-of-the-art dense vector models, such as in the DBPedia dataset. This indicates a certain level of complementarity between them. Intuitively, for some extremely short user inputs, the vectors generated by dense vector models might have significant semantic uncertainty, where overlaying with a sparse vector model could be beneficial. Additionally, sparse vector retrieval still maintains interpretability, and you can still observe the scoring calculation through the explanation command. To take advantage of both methods, OpenSearch has already introduced a built-in feature called hybrid search.

How to combine dense and sparse?

1. Deploy a dense vector model

To get more valuable test results, we selected Cohere-embed-multilingual-v3.0, which is one of several popular models used in production for dense vectors. We can access it through Amazon Bedrock and use the following two functions to create a connector for bedrock-cohere and then register it as a model in OpenSearch. You can get its model ID from the response.

def create_bedrock_cohere_connector(account_id, aos_endpoint, input_type='search_document'):
    # input_type could be search_document | search_query
    service = 'es'
    session = boto3.Session()
    credentials = session.get_credentials()
    region = session.region_name
    awsauth = AWS4Auth(credentials.access_key, credentials.secret_key, region, service, session_token=credentials.token)

    path = '/_plugins/_ml/connectors/_create'
    url = 'https://' + aos_endpoint + path

    role_name = "OpenSearchAndBedrockRole"
    role_arn = "arn:aws:iam::{}:role/{}".format(account_id, role_name)
    model_name = "cohere.embed-multilingual-v3"

    bedrock_url = "https://bedrock-runtime.{}.amazonaws.com/model/{}/invoke".format(region, model_name)

    payload = {
      "name": "Amazon Bedrock Connector: Cohere doc embedding",
      "description": "The connector to the Bedrock Cohere multilingual doc embedding model",
      "version": 1,
      "protocol": "aws_sigv4",
      "parameters": {
        "region": region,
        "service_name": "bedrock"
      },
      "credential": {
        "roleArn": role_arn
      },
      "actions": [
        {
          "action_type": "predict",
          "method": "POST",
          "url": bedrock_url,
          "headers": {
            "content-type": "application/json",
            "x-amz-content-sha256": "required"
          },
          "request_body": "{ \"texts\": ${parameters.texts}, \"input_type\": \"search_document\" }",
          "pre_process_function": "connector.pre_process.cohere.embedding",
          "post_process_function": "connector.post_process.cohere.embedding"
        }
      ]
    }
    headers = {"Content-Type": "application/json"}

    r = requests.post(url, auth=awsauth, json=payload, headers=headers)
    return json.loads(r.text)["connector_id"]
    
def register_and_deploy_aos_model(aos_client, model_name, model_group_id, description, connecter_id):
    request_body = {
        "name": model_name,
        "function_name": "remote",
        "model_group_id": model_group_id,
        "description": description,
        "connector_id": connecter_id
    }

    response = aos_client.transport.perform_request(
        method="POST",
        url=f"/_plugins/_ml/models/_register?deploy=true",
        body=json.dumps(request_body)
    )

    returnresponse 

2. Deploy a sparse vector model

Currently, you can’t deploy the sparse vector model in an OpenSearch Service domain. You must deploy it in Amazon SageMaker first, then integrate it through an OpenSearch Service model connector. For more information, see Amazon OpenSearch Service ML connectors for AWS services.

Complete the following steps:

2.1 On the OpenSearch Service console, choose Integrations in the navigation pane.

2.2 Under Integration with Sparse Encoders through Amazon SageMaker, choose to configure a VPC domain or public domain.

Next, you configure the AWS CloudFormation template.

2.3 Enter the parameters as shown in the following screenshot.

2.4 Get the sparse model ID from the stack output.

3. Set up pipelines for ingestion and search

Use the following code to create pipelines for ingestion and search. With these two pipelines, there’s no need to perform model inference, just text field ingestion.

PUT /_ingest/pipeline/neural-sparse-pipeline
{
  "description": "neural sparse encoding pipeline",
  "processors" : [
    {
      "sparse_encoding": {
        "model_id": "<nerual_sparse_model_id>",
        "field_map": {
           "content": "sparse_embedding"
        }
      }
    },
    {
      "text_embedding": {
        "model_id": "<cohere_ingest_model_id>",
        "field_map": {
          "doc": "dense_embedding"
        }
      }
    }
  ]
}

PUT /_search/pipeline/hybird-search-pipeline
{
  "description": "Post processor for hybrid search",
  "phase_results_processors": [
    {
      "normalization-processor": {
        "normalization": {
          "technique": "l2"
        },
        "combination": {
          "technique": "arithmetic_mean",
          "parameters": {
            "weights": [
              0.5,
              0.5
            ]
          }
        }
      }
    }
  ]
}

4. Create an OpenSearch index with dense and sparse vectors

Use the following code to create an OpenSearch index with dense and sparse vectors. You must specify the default_pipeline as the ingestion pipeline created in the previous step.

PUT {index-name}
{
    "settings" : {
        "index":{
            "number_of_shards" : 1,
            "number_of_replicas" : 0,
            "knn": "true",
            "knn.algo_param.ef_search": 32
        },
        "default_pipeline": "neural-sparse-pipeline"
    },
    "mappings": {
        "properties": {
            "content": {"type": "text", "analyzer": "ik_max_word", "search_analyzer": "ik_smart"},
            "dense_embedding": {
                "type": "knn_vector",
                "dimension": 1024,
                "method": {
                    "name": "hnsw",
                    "space_type": "cosinesimil",
                    "engine": "nmslib",
                    "parameters": {
                        "ef_construction": 512,
                        "m": 32
                    }
                }            
            },
            "sparse_embedding": {
                "type": "rank_features"
            }
        }
    }
}

Testing methodology

1. Experimental data selection

For retrieval evaluation, we used to use the datasets from BeIR. But not all datasets from BeIR are suitable for RAG. To mimic the knowledge retrieval scenario, we choose BeIR/fiqa and squad_v2 as our experimental datasets. The schema of its data is shown in the following figures.

The following is a data preview of squad_v2.

The following is a query preview of BeIR/fiqa.

The following is a corpus preview of BeIR/fiqa.

You can find question and context equivalent fields in the BeIR/fiqa datasets. This is almost the same as the knowledge recall in RAG. In subsequent experiments, we input the context field into the index of OpenSearch as text content, and use the question field as a query for the retrieval test.

2. Test data ingestion

The following script ingests data into the OpenSearch Service domain:

import json
from setup_model_and_pipeline import get_aos_client
from beir.datasets.data_loader import GenericDataLoader
from beir import LoggingHandler, util

aos_client = get_aos_client(aos_endpoint)

def ingest_dataset(corpus, aos_client, index_name, bulk_size=50):
    i=0
    bulk_body=[]
    for _id , body in tqdm(corpus.items()):
        text=body["title"]+" "+body["text"]
        bulk_body.append({ "index" : { "_index" : index_name, "_id" : _id } })
        bulk_body.append({ "content" : text })
        i+=1
        if i % bulk_size==0:
            response=aos_client.bulk(bulk_body,request_timeout=100)
            try:
                assert response["errors"]==False
            except:
                print("there is errors")
                print(response)
                time.sleep(1)
                response = aos_client.bulk(bulk_body,request_timeout=100)
            bulk_body=[]
        
    response=aos_client.bulk(bulk_body,request_timeout=100)
    assert response["errors"]==False
    aos_client.indices.refresh(index=index_name)

url = f"https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/{dataset_name}.zip"
data_path = util.download_and_unzip(url, data_root_dir)
corpus, queries, qrels = GenericDataLoader(data_folder=data_path).load(split="test")
ingest_dataset(corpus, aos_client=aos_client, index_name=index_name)

3. Performance evaluation of retrieval

In RAG knowledge retrieval, we usually focus on the relevance of top results, so our evaluation uses recall@4 as the metric indicator. The whole test will include various retrieval methods to compare, such as bm25_only, sparse_only, dense_only, hybrid_sparse_dense, and hybrid_dense_bm25.

The following script uses hybrid_sparse_dense to demonstrate the evaluation logic:

def search_by_dense_sparse(aos_client, index_name, query, sparse_model_id, dense_model_id, topk=4):
    request_body = {
      "size": topk,
      "query": {
        "hybrid": {
          "queries": [
            {
              "neural_sparse": {
                  "sparse_embedding": {
                    "query_text": query,
                    "model_id": sparse_model_id,
                    "max_token_score": 3.5
                  }
              }
            },
            {
              "neural": {
                  "dense_embedding": {
                      "query_text": query,
                      "model_id": dense_model_id,
                      "k": 10
                    }
                }
            }
          ]
        }
      }
    }

    response = aos_client.transport.perform_request(
        method="GET",
        url=f"/{index_name}/_search?search_pipeline=hybird-search-pipeline",
        body=json.dumps(request_body)
    )

    return response["hits"]["hits"]
    
url = f"https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/{dataset_name}.zip"
data_path = util.download_and_unzip(url, data_root_dir)
corpus, queries, qrels = GenericDataLoader(data_folder=data_path).load(split="test")
run_res={}
for _id, query in tqdm(queries.items()):
    hits = search_by_dense_sparse(aos_client, index_name, query, sparse_model_id, dense_model_id, topk)
    run_res[_id]={item["_id"]:item["_score"] for item in hits}
    
for query_id, doc_dict in tqdm(run_res.items()):
    if query_id in doc_dict:
        doc_dict.pop(query_id)
res = EvaluateRetrieval.evaluate(qrels, run_res, [1, 4, 10])
print("search_by_dense_sparse:")
print(res)

Results

In the context of RAG, usually the developer doesn’t pay attention to the metric NDCG@10; the LLM will pick up the relevant context automatically. We care more about the recall metric. Based on our experience of RAG, we measured recall@1, recall@4, and recall@10 for your reference.

The dataset BeIR/fiqa is mainly used for evaluation of retrieval, whereas squad_v2 is mainly used for evaluation of reading comprehension. In terms of retrieval, squad_v2 is much less complicated than BeIR/fiqa. In the real RAG context, the difficulty of retrieval may not be as high as with BeIR/fiqa, so we evaluate both datasets.

The hybird_dense_sparse metric is always beneficial. The following table shows our results.

Dataset BeIR/fiqa squad_v2
Method\Metric Recall@1 Recall@4 Recall@10 Recall@1 Recall@4 Recall@10
bm25 0.112 0.215 0.297 0.59 0.771 0.851
dense 0.156 0.316 0.398 0.671 0.872 0.925
sparse 0.196 0.334 0.438 0.684 0.865 0.926
hybird_dense_sparse 0.203 0.362 0.456 0.704 0.885 0.942
hybird_dense_bm25 0.156 0.316 0.394 0.671 0.871 0.925

Conclusion

The new neural sparse search feature in OpenSearch Service version 2.11, when combined with dense vector retrieval, can significantly improve the effectiveness of knowledge retrieval in RAG scenarios. Compared to the combination of bm25 and dense vector retrieval, it’s more straightforward to use and more likely to achieve better results.

OpenSearch Service version 2.12 has recently upgraded its Lucene engine, significantly enhancing the throughput and latency performance of neural sparse search. But the current neural sparse search only supports English. In the future, other languages might be supported. As the technology continues to evolve, it stands to become a popular and widely applicable way to enhance retrieval performance.


About the Author

YuanBo Li is a Specialist Solution Architect in GenAI/AIML at Amazon Web Services. His interests include RAG (Retrieval-Augmented Generation) and Agent technologies within the field of GenAI, and he dedicated to proposing innovative GenAI technical solutions tailored to meet diverse business needs.

Charlie Yang is an AWS engineering manager with the OpenSearch Project. He focuses on machine learning, search relevance, and performance optimization.

River Xie is a Gen AI specialist solution architecture at Amazon Web Services. River is interested in Agent/Mutli Agent workflow, Large Language Model inference optimization, and passionate about leveraging cutting-edge Generative AI technologies to develop modern applications that solve complex business challenges.

Ren Guo is a manager of Generative AI Specialist Solution Architect Team for the domains of AIML and Data at AWS, Greater China Region.

Integrate Tableau and Microsoft Entra ID with Amazon Redshift using AWS IAM Identity Center

Post Syndicated from Debu Panda original https://aws.amazon.com/blogs/big-data/integrate-tableau-and-microsoft-entra-id-with-amazon-redshift-using-aws-iam-identity-center/

This post is co-written with Sid Wray, Jade Koskela, and Ravi Bhattiprolu from SalesForce.

Amazon Redshift and Tableau empower data analysis. Amazon Redshift is a cloud data warehouse that processes complex queries at scale and with speed. Its advanced query optimization serves results to Tableau. Tableau’s extensive capabilities and enterprise connectivity help analysts efficiently prepare, explore, and share data insights company-wide.

Customers can integrate Amazon Redshift with Tableau using single sign-on (SSO) capabilities enabled by AWS IAM Identity Center integration with trusted identity propagation. You can use this to seamlessly implement authentication with third-party identity providers (IdP) and authorization with Redshift. It positions Amazon Redshift as an AWS managed application, allowing you to take full advantage of the trusted identity propagation feature.

Amazon Web Services (AWS) collaborated with Tableau to enable SSO support for accessing Amazon Redshift from Tableau. Both Tableau Desktop 2023.3.9 and Tableau Server 2023.3.9 releases support trusted identity propagation with IAM Identity Center. This SSO integration is available for Tableau Desktop, Tableau Server, and Tableau Prep.

This blog post provides a step-by-step guide to integrating IAM Identity Center with Microsoft Entra ID as the IdP and configuring Amazon Redshift as an AWS managed application. Additionally, you’ll learn how to set up the Amazon Redshift driver in Tableau, enabling SSO directly within Tableau Desktop.

Solution overview

The following diagram illustrates the architecture of the Tableau SSO integration with Amazon Redshift, IAM Identity Center, and Microsoft Entra ID.

Figure 1: Solution overview for Tableau integration with Amazon Redshift using IAM Identity Center and Microsoft Entra ID

The solution depicted in Figure 1 includes the following steps:

  1. The user configures Tableau to access Amazon Redshift using IAM Identity Center.
  2. On a user sign-in attempt, Tableau initiates a browser-based OAuth flow and redirects the user to the Microsoft Entra ID sign-in page to enter the sign-in credentials.
  3. After successful authentication, Microsoft Entra ID issues authentication tokens (ID and access token) to Tableau.
  4. The Amazon Redshift driver then makes a call to the Amazon Redshift-enabled Identity Center application and forwards the access token.
  5. Amazon Redshift passes the token to IAM Identity Center for validation.
  6. IAM Identity Center first validates the token using the OpenID Connect (OIDC) discovery connection to the trusted token issuer (TTI) and returns an IAM Identity Center generated access token for the same user. In Figure 1, the TTI is the Microsoft Entra ID server.
  7. Amazon Redshift then uses the access token to obtain the user and group membership information from Identity Center.
  8. The Tableau user will be able to connect with Amazon Redshift and access data based on the user and group membership returned from IAM Identity Center.

Prerequisites

Before you begin implementing the solution, you must have the following in place:

Walkthrough

In this walkthrough, you will use the following steps to build the solution:

  1. Set up the Microsoft Entra ID OIDC application
  2. Collect Microsoft Entra ID information
  3. Set up a trusted token issuer in IAM Identity Center
  4. Set up client connections and trusted token issuers
  5. Set up the Tableau OAuth config files for Microsoft Entra ID
  6. Install the Tableau OAuth config file for Tableau Desktop
  7. Set up the Tableau OAuth config file for Tableau Server or Tableau Cloud
  8. Federate to Amazon Redshift from Tableau Desktop
  9. Federate to Amazon Redshift from Tableau Server

Set up the Microsoft Entra ID OIDC application

To create your Microsoft Entra application and service principal, follow these steps:

  1. Sign in to the Microsoft Entra admin center as Cloud Application Administrator (at the least).
  2. Browse to App registrations under Manage, and choose New registration.
  3. Enter a name for the application. For example, Tableau-OIDC-App.
  4. Select a supported account type, which determines who can use the application. For this example, select the first option in the list.
  5. Under Redirect URI, select Web for the type of application you want to create. Enter the URI where the access token is sent to. In this example, you’re using localhost, so enter http://localhost:55556/Callback and http://localhost/auth/add_oauth_token.
  6. Choose Register.
  7. In the navigation pane, choose Certificates & secrets.
  8. Choose New client secret.
  9. Enter a Description and select an expiration for the secret or specify a custom lifetime. For this example, keep the Microsoft recommended default expiration value of 6 months. Choose Add.
  10. Copy the secret value.
    Note: It will only be presented one time; after that you cannot read it.
  11. In the navigation pane, under Manage, choose Expose an API.
  12. If you’re setting up for the first time, you can see Set to the right of Application ID URI.
  13. Choose Set, and then choose Save.
  14. After the application ID URI is set up, choose Add a scope.
  15. For Scope name, enter a name. For example, redshift_login.
  16. For Admin consent display name, enter a display name. For example, redshift_login.
  17. For Admin consent description, enter a description of the scope.
  18. Choose Add scope.

For more information about setting up the Microsoft Entra app, see Register a Microsoft Entra app and create a service principal.

Collect Microsoft Entra ID information

To configure your IdP with IAM Identity Center and Amazon Redshift, collect the following parameters from Microsoft Entra ID. If you don’t have these parameters, contact your Microsoft Entra ID admin.

  1. Tenant ID,Client ID and Audience value: To get these values:
    1. Sign in to the Azure portal with your Microsoft account.
    2. Under Manage, choose App registrations.
    3. Choose the application that you created in previous sections.
    4. On the left panel, choose Overview, a new page will appear containing the Essentials section. You can find the Tenant ID,Client ID and Audience value (Application ID URI) as shown in the following figure:

      Figure 2: Overview section of OIDC application

  1. Scope: To find your scope value:
    1. In the navigation pane of the OIDC application, under Manage, choose Expose an API.
    2. You will find the value under Scopes as shown in the following figure:

      Figure 3: Application scope

Set up a trusted token issuer in IAM Identity Center

At this point, you have finished configurations in the Entra ID console; now you’re ready to add Entra ID as a TTI. You will start by adding a TTI so you can exchange tokens. In this step, you will create a TTI in the centralized management account. To create a TTI, follow these steps:

  1. Open the AWS Management Console and navigate to IAM Identity Center, and then to the Settings
  2. Select the Authentication tab and under Trusted token issuers, choose Create trusted token issuer.
  3. On the Set up an external IdP to issue trusted tokens page, under Trusted token issuer details, do the following:
    1. For Issuer URL, enter the OIDC discovery URL of the external IdP that will issue tokens for trusted identity propagation. The URL would be: https://sts.windows.net/<tenantid>/. To find your Microsoft Entra tenant ID, see Collect Microsoft Entra ID information.
    2. For Trusted token issuer name, enter a name to identify this TTI in IAM Identity Center and in the application console.
    3. Under Map attributes, do the following:
      1. For Identity provider attribute, select an attribute from the list to map to an attribute in the Identity Center identity store. You can choose Email, Object Identifier, Subject, and Other. This example uses Other where we’re specifying the upn (user principal name) as the Identity provider attribute to map with Email from the IAM identity Center attribute.
      2. For IAM Identity Center attribute, select the corresponding attribute for the attribute mapping.
    4. Under Tags (optional), choose Add new tag, specify a value for Key, and optionally for Value. For information about tags, see Tagging AWS IAM Identity Center resources.

Figure 4 that follows shows the set up for TTI.

Figure 4: Create a trusted token issuer

  1. Choose Create trusted token issuer.

Set up client connections and trusted token issuers

A third-party application (such as Tableau) that isn’t managed by AWS exchanges the external token (JSON Web Token (JWT) for an IAM Identity Center token before calling AWS services.

The JWT must contain a subject (sub) claim, an audience (aud) claim, an issuer (iss), a user attribute claim, and a JWT ID (JTI) claim. The audience is a value that represents the AWS service that the application will use, and the audience claim value must match the value that’s configured in the Redshift application that exchanges the token.

In this section, you will specify the audience claim in the Redshift application, which you will get from Microsoft Entra ID. You will configure the Redshift application in the member account where the Redshift cluster or serverless instance is.

  1. Select IAM Identity Center connection from Amazon Redshift console menu.

Figure 5: Redshift IAM Identity Center connection

  1. Select the Amazon Redshift application that you created as part of the prerequisites.
  2. Select the Client connections tab and choose Edit.
  3. Choose Yes under Configure client connections that use third-party IdPs.
  4. Select the checkbox for Trusted token issuer that you created in the previous section.
  5. Enter the aud claim value under Configure selected trusted token issuers. For example, api://1230a234-b456-7890-99c9-a12345bcc123. To get the audience value, see Collect Microsoft Entra ID information.
  6. Choose Save.

Figure 6: Adding an audience claim for the TTI

Your IAM Identity Center, Amazon Redshift, and Microsoft Entra ID configuration is complete. Next, you need to configure Tableau.

Set up the Tableau OAuth config files for Microsoft Entra ID

To integrate Tableau with Amazon Redshift using IAM Identity Center, you need to use a custom XML. In this step, you use the following XML and replace the values starting with the $ sign and highlighted in bold. The rest of the values can be kept as they are, or you can modify them based on your use case. For detailed information on each of the elements in the XML file, see the Tableau documentation on GitHub.

Note: The XML file will be used for all the Tableau products including Tableau Desktop, Server, and Cloud. You can use the following XML or you can refer to Tableau’s github.

<?xml version="1.0" encoding="utf-8"?>
<pluginOAuthConfig>
<dbclass>redshift</dbclass>
<!-- For configs embedded in the connector package, don't prefix with "custom_". For external configs, always prefix with "custom_". -->
<oauthConfigId>custom_redshift_azure</oauthConfigId>
<clientIdDesktop>$copy_client_id_from_azure_oidc_app</clientIdDesktop>
<clientSecretDesktop>$copy_client_secret_from_azure_oidc_app</clientSecretDesktop>
<redirectUrisDesktop>http://localhost:55556/Callback</redirectUrisDesktop>
<redirectUrisDesktop>http://localhost:55557/Callback</redirectUrisDesktop>
<redirectUrisDesktop>http://localhost:55558/Callback</redirectUrisDesktop>
<redirectUrisDesktop>http://localhost:55559/Callback</redirectUrisDesktop>
<!-- For multitenant apps use the common endpoint, for single tenant apps use the directory specific endpoint. -->
<authUri>https://login.microsoftonline.com/$azure_tenant_id/oauth2/v2.0/authorize</authUri>
<tokenUri>https://login.microsoftonline.com/$azure_tenant_id/oauth2/v2.0/token</tokenUri>
<scopes>openid</scopes>
<scopes>offline_access</scopes>
<scopes>email</scopes>
<!-- An example with a custom API, which was required at the time of writing for integration with AWS IAM IDC. -->
<scopes>$scope_from_azure_oidc_app</scopes>
<capabilities>
<entry>
<key>OAUTH_CAP_REQUIRES_PROMPT_SELECT_ACCOUNT</key>
<value>true</value>
</entry>
<entry>
<key>OAUTH_CAP_REQUIRE_PKCE</key>
<value>true</value>
</entry>
<entry>
<key>OAUTH_CAP_PKCE_REQUIRES_CODE_CHALLENGE_METHOD</key>
<value>true</value>
</entry>
<entry>
<key>OAUTH_CAP_SUPPORTS_STATE</key>
<value>true</value>
</entry>
<entry>
<key>OAUTH_CAP_CLIENT_SECRET_IN_URL_QUERY_PARAM</key>
<value>false</value>
</entry>
<entry>
<key>OAUTH_CAP_SUPPORTS_GET_USERINFO_FROM_ID_TOKEN</key>
<value>true</value>
</entry>
<!-- Depending on the Azure application, dynamic ports may not be allowed. Enable this if not allowed. -->
<entry>
<key>OAUTH_CAP_FIXED_PORT_IN_CALLBACK_URL</key>
<value>true</value>
</entry>
</capabilities>
<accessTokenResponseMaps>
<entry>
<key>ACCESSTOKEN</key>
<value>access_token</value>
</entry>
<entry>
<key>REFRESHTOKEN</key>
<value>refresh_token</value>
</entry>
<entry>
<key>access-token-issue-time</key>
<value>issued_at</value>
</entry>
<entry>
<key>id-token</key>
<value>id_token</value>
</entry>
<entry>
<key>username</key>
<value>email</value>
</entry>
<entry>
<key>access-token-expires-in</key>
<value>expires_in</value>
</entry>
</accessTokenResponseMaps>
</pluginOAuthConfig>

The following is an example XML file:

<?xml version="1.0" encoding="utf-8"?>
<pluginOAuthConfig>
<dbclass>redshift</dbclass>
<!-- For configs embedded in the connector package, don't prefix with "custom_". For external configs, always prefix with "custom_". -->
<oauthConfigId>custom_redshift_azure</oauthConfigId>
<clientIdDesktop>1230a234-b456-7890-99c9-a12345bcc123</clientIdDesktop>
<clientSecretDesktop>RdQbc~1234559xFX~c65737wOwjsdfdsg123bg2</clientSecretDesktop>
<redirectUrisDesktop>http://localhost:55556/Callback</redirectUrisDesktop>
<redirectUrisDesktop>http://localhost:55557/Callback</redirectUrisDesktop>
<redirectUrisDesktop>http://localhost:55558/Callback</redirectUrisDesktop>
<redirectUrisDesktop>http://localhost:55559/Callback</redirectUrisDesktop>
<!-- For multitenant apps use the common endpoint, for single tenant apps use the directory specific endpoint. -->
<authUri>https://login.microsoftonline.com/e12a1ab3-1234-12ab-12b3-1a5012221d12/oauth2/v2.0/authorize</authUri>
<tokenUri>https://login.microsoftonline.com/e12a1ab3-1234-12ab-12b3-1a5012221d12/oauth2/v2.0/token</tokenUri>
<scopes>openid</scopes>
<scopes>offline_access</scopes>
<scopes>email</scopes>
<!-- An example with a custom API, which was required at the time of writing for integration with AWS IAM IDC. -->
<scopes>api://1230a234-b456-7890-99c9-a12345bcc123/redshift_login</scopes>
<capabilities>
<entry>
<key>OAUTH_CAP_REQUIRES_PROMPT_SELECT_ACCOUNT</key>
<value>true</value>
</entry>
<entry>
<key>OAUTH_CAP_REQUIRE_PKCE</key>
<value>true</value>
</entry>
<entry>
<key>OAUTH_CAP_PKCE_REQUIRES_CODE_CHALLENGE_METHOD</key>
<value>true</value>
</entry>
<entry>
<key>OAUTH_CAP_SUPPORTS_STATE</key>
<value>true</value>
</entry>
<entry>
<key>OAUTH_CAP_CLIENT_SECRET_IN_URL_QUERY_PARAM</key>
<value>false</value>
</entry>
<entry>
<key>OAUTH_CAP_SUPPORTS_GET_USERINFO_FROM_ID_TOKEN</key>
<value>true</value>
</entry>
<!-- Depending on the Azure application, dynamic ports may not be allowed. Enable this if not allowed. -->
<entry>
<key>OAUTH_CAP_FIXED_PORT_IN_CALLBACK_URL</key>
<value>true</value>
</entry>
</capabilities>
<accessTokenResponseMaps>
<entry>
<key>ACCESSTOKEN</key>
<value>access_token</value>
</entry>
<entry>
<key>REFRESHTOKEN</key>
<value>refresh_token</value>
</entry>
<entry>
<key>access-token-issue-time</key>
<value>issued_at</value>
</entry>
<entry>
<key>id-token</key>
<value>id_token</value>
</entry>
<entry>
<key>username</key>
<value>email</value>
</entry>
<entry>
<key>access-token-expires-in</key>
<value>expires_in</value>
</entry>
</accessTokenResponseMaps>
</pluginOAuthConfig>

Install the Tableau OAuth config file for Tableau Desktop

After the configuration XML file is created, it must be copied to a location to be used by Amazon Redshift Connector from Tableau Desktop. Save the file from the previous step as .xml and save it under Documents\My Tableau Repository\OAuthConfigs.

Note: Currently, this integration isn’t supported in macOS because the Redshift ODBC 2.X driver isn’t supported yet for MAC. It will be supported soon.

Set up the Tableau OAuth config file for Tableau Server or Tableau Cloud

To integrate with Amazon Redshift using IAM Identity Center authentication, you must install the Tableau OAuth config file in Tableau Server or Tableau Cloud.

  1. Sign in to the Tableau Server or Tableau Cloud using admin credentials.
  2. Navigate to Settings.
  3. Go to OAuth Clients Registry and select Add OAuth Client
  4. Choose following settings:
    1. Connection Type: Amazon Redshift
    2. OAuth Provider: Custom_IdP
    3. Client Id: Enter your IdP client ID value
    4. Client Secret: Enter your client secret value
    5. Redirect URL: Enter http://localhost/auth/add_oauth_token. This example uses localhost for testing in a local environment. You should use the full hostname with https.
    6. Choose OAuth Config File. Select the XML file that you configured in the previous section.
    7. Select Add OAuth Client and choose Save.

Figure 7: Create an OAuth connection in Tableau Server or Cloud

Federate to Amazon Redshift from Tableau Desktop

Now you’re ready to connect to Amazon Redshift from Tableau as an Entra ID federated user. In this step, you create a Tableau Desktop report and publish it to Tableau Server.

  1. Open Tableau Desktop.
  2. Select Amazon Redshift Connector and enter the following values:
    1. Server: Enter the name of the server that hosts the database and the name of the database you want to connect to.
    2. Port: Enter 5439.
    3. Database: Enter your database name. This example uses dev.
    4. Authentication: Select OAuth.
    5. Federation Type: Select Identity Center.
    6. Identity Center Namespace: You can leave this value blank.
    7. OAuth Provider: This value should automatically be pulled from your configured XML. It will be the value from the element oauthConfigId.
    8. Select Require SSL.
    9. Choose Sign in.

      Figure 8: Tableau Desktop OAuth connection

  1. Enter your IdP credentials in the browser pop-up window.

    Figure 9: Microsoft Entra sign in page

  2. When authentication is successful, you will see the message shown in Figure 10 that follows.

    Figure 10: Successful authentication using Tableau

Congratulations! You’re signed in using the IAM Identity Center integration with Amazon Redshift. Now you’re ready to explore and analyze your data using Tableau Desktop.

Figure 11: Successful connection using Tableau Desktop

After signing in, you can create your own Tableau Report on the desktop version and publish it to your Tableau Server. For this example, we created and published a report named SalesReport.

Federate to Amazon Redshift from Tableau Server

After you have published the report from Tableau Desktop to Tableau Server, sign in as a non-admin user and view the published report (SalesReport in this example) using IAM Identity Center authentication.

  1. Sign in to the Tableau Server site as a non-admin user.
  2. Navigate to Explore and go to the folder where your published report is stored.
  3. Select the report and choose Sign In.

    Figure 12: User audit in sys_query_history

  4. To authenticate, enter your non-admin Microsoft Entra ID (Azure) credentials in the browser pop-up.

    Figure 13: Tableau Server sign In

  5. After your authentication is successful, you can access the report.

    Figure 14: Tableau report

Verify user identity from Amazon Redshift

As an optional step, you can audit the federated IAM Identity Center user from Amazon Redshift.

Figure 15 is a screenshot from the Amazon Redshift system table (sys_query_history) showing that user Ethan from Microsoft Entra ID is accessing the sales report.

select distinct user_id, pg.usename as username, trim(query_text) as query_text
from sys_query_history sys
join pg_user_info pg
on sys.user_id=pg.usesysid
where query_id=<query_id> and usesysid=<federateduser_id> and query_type='SELECT'
order by start_time desc
;

Figure 15: User audit in sys_query_history

Clean up

Complete the following steps to clean up your resources:

  1. Delete the IdP applications that you created to integrate with IAM Identity Center.
  2. Delete the IAM Identity Center configuration.
  3. Delete the Amazon Redshift application and the Amazon Redshift provisioned cluster or serverless instance that you created for testing.
  4. Delete the AWS Identity and Access Management (IAM) role and IAM policy that you created as part of the prerequisites for IAM Identity Center and Amazon Redshift integration.
  5. Delete the permission set from IAM Identity Center that you created for Amazon Redshift Query Editor V2 in the management account.

Conclusion

This post explored a streamlined approach to access management for data analytics by using Tableau’s support for OIDC for SSO. The solution facilitates federated user authentication, where user identities from an external IdP are trusted and propagated to Amazon Redshift. You learned how to configure Tableau Desktop and Tableau Server to seamlessly integrate with Amazon Redshift using IAM Identity Center for SSO. By harnessing this integration between a third-party IdP and IAM Identity Center, users can securely access Amazon Redshift data sources within Tableau without managing separate database credentials.

The following are key resources to learn more about Amazon Redshift integration with IAM Identity Center:


About the Authors

Debu-PandaDebu Panda is a Senior Manager, Product Management at AWS. He is an industry leader in analytics, application platform, and database technologies, and has more than 25 years of experience in the IT world.

Sid Wray is a Senior Product Manager at Salesforce based in the Pacific Northwest with nearly 20 years of experience in Digital Advertising, Data Analytics, Connectivity Integration and Identity and Access Management. He currently focuses on supporting ISV partners for Salesforce Data Cloud.

Adiascar Cisneros is a Tableau Senior Product Manager based in Atlanta, GA. He focuses on the integration of the Tableau Platform with AWS services to amplify the value users get from our products and accelerate their journey to valuable, actionable insights. His background includes analytics, infrastructure, network security, and migrations.

Jade Koskela is a Principal Software Engineer at Salesforce. He has over a decade of experience building Tableau with a focus on areas including data connectivity, authentication, and identity federation.

Harshida Patel is a Principal Solutions Architect, Analytics with AWS.

Maneesh Sharma is a Senior Database Engineer at AWS with more than a decade of experience designing and implementing large-scale data warehouse and analytics solutions. He collaborates with various Amazon Redshift Partners and customers to drive better integration.

Ravi Bhattiprolu is a Senior Partner Solutions Architect at AWS. He collaborates with strategic independent software vendor (ISV) partners like Salesforce and Tableau to design and deliver innovative, well-architected cloud products, integrations, and solutions to help joint AWS customers achieve their business goals.

Automatically replicate your card payment keys across AWS Regions

Post Syndicated from Ruy Cavalcanti original https://aws.amazon.com/blogs/security/automatically-replicate-your-card-payment-keys-across-aws-regions/

In this blog post, I dive into a cross-Region replication (CRR) solution for card payment keys, with a specific focus on the powerful capabilities of AWS Payment Cryptography, showing how your card payment keys can be securely transported and stored.

In today’s digital landscape, where online transactions have become an integral part of our daily lives, ensuring the seamless operation and security of card payment transactions is of utmost importance. As customer expectations for uninterrupted service and data protection continue to rise, organizations are faced with the challenge of implementing robust security measures and disaster recovery strategies that can withstand even the most severe disruptions.

For large enterprises dealing with card payments, the stakes are even higher. These organizations often have stringent requirements related to disaster recovery (DR), resilience, and availability, where even a 99.99 percent uptime isn’t enough. Additionally, because these enterprises deliver their services globally, they need to ensure that their payment applications and the associated card payment keys, which are crucial for securing card data and payment transactions, are securely replicated and stored across AWS Regions.

Furthermore, I explore an event-driven, serverless architecture and the use of AWS PrivateLink to securely move keys through the AWS backbone, providing additional layers of security and efficiency. Overall, this blog post offers valuable insights into using AWS services for secure and resilient data management across AWS Regions.

Card payment key management

If you examine key management, you will notice that card payment keys are shared between devices and third parties today the same as they were around 40 years ago.

A key ceremony is the process held when parties want to securely exchange keys. It involves key custodians responsible for transporting and entering, key components that have been printed on pieces of paper into a hardware security module (HSM). This is necessary to share initial key encryption keys.

Let’s look at the main issues with the current key ceremony process:

  • It requires a secure room with a network-disconnected Payment HSM
  • The logistics are difficult: Three key custodians in the same place at the same time
  • Timewise, it usually takes weeks to have all custodians available, which can interfere with a project release
  • The cost of the operation which includes maintaining a secure room and the travel of the key custodians
  • Lost or stolen key components

Now, let’s consider the working keys used to encrypt sensitive card data. They rely on those initial keys to protect them. If the initial keys are compromised, their associated working keys are also considered compromised. I also see companies using key management standards from the 1990s, such as ANSI X9.17 / FIPS 171, to share working keys. NIST withdrew the FIPS 171 standard in 2005.

Analyzing the current scenario, you’ll notice security risks because of the way keys are shared today and sometimes because organizations are using deprecated standards.

So, let’s get card payment security into the twenty-first century!

Solution overview

AWS Payment Cryptography is a highly available and scalable service that currently operates within the scope of an individual Region. This means that the encryption keys and associated metadata are replicated across multiple Availability Zones within that Region, providing redundancy and minimizing the risk of downtime caused by failures within a single Region.

While this regional replication across multiple Availability Zones provides a higher level of availability and fault tolerance compared to traditional on-premises HSM solutions, some customers with stringent business continuity requirements have requested support for multi-Region replication.

By spanning multiple Regions, organizations can achieve a higher level of resilience and disaster recovery capabilities because data and services can be replicated and failover mechanisms can be implemented across geographically dispersed locations.

This Payment Cryptography CRR solution addresses the critical requirements of high availability, resilience, and disaster recovery for card payment transactions. By replicating encryption keys and associated metadata across multiple Regions, you can maintain uninterrupted access to payment services, even in the event of a regional outage or disaster.

Note: When planning your replication strategy, check the available Payment Cryptography service endpoints.

Here’s how it works:

  1. Primary Region: Encryption keys are generated and managed in a primary Region using Payment Cryptography.
  2. Replication: The generated encryption keys are securely replicated to a secondary Region, creating redundant copies for failover purposes.
  3. Failover: In the event of a regional outage or disaster in the primary Region, payment operations can seamlessly failover to a secondary Region, using the replicated encryption keys to continue processing transactions without interruption.

This cross-Region replication approach enhances availability and resilience and facilitates robust disaster recovery strategies, allowing organizations to quickly restore payment services in a new Region if necessary.

Figure 1: Cross-Region replication (CRR) solution architecture

Figure 1: Cross-Region replication (CRR) solution architecture

The elements of the CRR architecture are as follows:

  1. Payment Cryptography control plane events are sent to an AWS CloudTrail trail.
  2. The CloudTrail trail is configured to send logs to an Amazon CloudWatch Logs log group.
  3. This log group contains an AWS Lambda subscription filter that filters the following events from Payment Cryptography: CreateKey, DeleteKey and ImportKey.
  4. When one of the events is detected, a Lambda function is launched to start key replication.
  5. The Lambda function performs key export and import processes in a secure way using TR-31, which uses an initial key securely generated and shared using TR-34. This initial key is generated when the solution is enabled.
  6. Communication between the primary (origin) Region and the Payment Cryptography service endpoint at the secondary (destination) Region is done through an Amazon Virtual Private Cloud (Amazon VPC) peering connection, over VPC interface endpoints from PrivateLink.
  7. Metadata information is saved on Amazon DynamoDB tables.

Walkthrough

The CRR solution is deployed in several steps, and it’s essential to understand the underlying processes involved, particularly TR-34 (ANSI X9.24-2) and TR-31 (ANSI X9.143-2022), which play crucial roles in ensuring the secure replication of card payment keys across Regions.

  1. Clone the solution repository from GitHub.
  2. Verify that the prerequisites are in place.
  3. Define which Region the AWS Cloud Development Kit (AWS CDK) stack will be deployed in. This is the primary Region that Payment Cryptography keys will be replicated from.
  4. Enable CRR. This step involves the TR-34 process, which is a widely adopted standard for the secure distribution of symmetric keys using asymmetric techniques. In the context of this solution, TR-34 is used to securely exchange the initial key-encrypting key (KEK) between the primary and secondary Regions. This KEK is then used to encrypt and securely transmit the card payment keys (also called working keys) during the replication process. TR-34 uses asymmetric cryptographic algorithms, such as RSA, to maintain the confidentiality, integrity and authenticity of the exchanged keys.

    Figure 2: TR-34 import key process

    Figure 2: TR-34 import key process

  5. Create, import, and delete keys in the primary Region to check that keys will be automatically replicated. This step uses the TR-31 process, which is a standard for the secure exchange of cryptographic keys and related data. In this solution, TR-31 is employed to securely replicate the card payment keys from the primary Region to the secondary Region, using the previously established KEK for encryption. TR-31 incorporates various cryptographic algorithms, such as AES and HMAC, to protect the confidentiality and integrity of the replicated keys during transit

    Figure 3: TR-31 import key process

    Figure 3: TR-31 import key process

  6. Clean up when needed.

Detailed information about key blocks can be found on the related ANSI documentation. To summarize, the TR-31 key block specification and the TR-34 key block specification, which is based on the TR-31 key block specification, consists of three parts:

  1. Key block header (KBH) – Contains attribute information about the key and the key block.
  2. Encrypted data – This is the key (initial key encryption key for TR-34 and working key for TR-31) being exchanged.
  3. Signature (MAC) – Calculated over the KBH and encrypted data.

Figure 4 presents the entire TR-31 and TR-34 key block parts. It is also called key binding method, which is the technique used to protect the key block secrecy and integrity. On both key blocks, the key, its length, and padding fields are encrypted, maintaining the key block secrecy. Signing of the entire key block fields verifies its integrity and authenticity. The signed result is appended to the end of the block.

Figure 4: TR-31 and TR-34 key block formats

Figure 4: TR-31 and TR-34 key block formats

By adhering to industry-standard protocols like TR-34 and TR-31, this solution helps to ensure that the replication of card payment keys across Regions is performed in a secure manner that delivers confidentiality, integrity, and authenticity. It’s worth mentioning that Payment Cryptography fully supports and implements these standards, providing a solution that adheres to PCI standards for secure key management and replication.

If you want to dive deep into this key management processes, see the service documentation page on import and export keys.

Prerequisites

The Payment Cryptography CRR solution will be deployed through the AWS CDK. The code was developed in Python and assumes that there is a python3 executable in your path. It’s also assumed that the AWS Command Line Interface (AWS CLI) and AWS CDK executables exist in the path system variable of your local computer.

Download and install the following:

It’s recommended that you use the latest stable versions. Tests were performed using the following versions:

  • Python: 3.12.2 (MacOS version)
  • jq: 1.7.1 (MacOS version)
  • AWS CLI: aws-cli/2.15.29 Python/3.11.8 Darwin/22.6.0 exe/x86_64 prompt/off
  • AWS CDK: 2.132.1 (build 9df7dd3)

To set up access to your AWS account, see Configure the AWS CLI.

Note: Tests and commands in the following sections where run on a MacOS operating system.

Deploy the primary resources

The solution is deployed in two main parts:

  1. Primary Region resources deployment
  2. CRR setup, where a secondary Region is defined for deployment of the necessary resources

This section will cover the first part:

Figure 5: Primary Region resources

Figure 5: Primary Region resources

Figure 5 shows the resources that will be deployed in the primary Region:

  1. A CloudTrail trail for write-only log events.
  2. CloudWatch Logs log group associated with the CloudTrail trail. An Amazon Simple Storage Service (Amazon S3) bucket is also created to store this trail’s log events.
  3. A VPC, private subnets, a security group, Lambda functions, and VPC endpoint resources to address private communication inside the AWS backbone.
  4. DynamoDB tables and DynamoDB Streams to manage key replication and orchestrate the solution deployment to the secondary Region.
  5. Lambda functions responsible for managing and orchestrating the solution deployment and setup.

Some parameters can be configured before deployment. They’re located in the cdk.json file (part of the GitHub solution to be downloaded) inside the solution base directory.

The parameters reside inside the context.ENVIRONMENTS.dev key:

{
  ...
  "context": {
    ...
    "ENVIRONMENTS": {
      "dev": {
        "origin_vpc_cidr": "10.2.0.0/16",
        "origin_vpc_name": "origin-vpc",
        "origin_subnets_mask": 22,
        "origin_subnets_prefix_name": "origin-subnet-private"
      }
    }
  }
}

Note: You can change the parameters origin_vpc_cidr, origin_vpc_name and origin_subnets_prefix_name.

Validate that there aren’t VPCs already created with the same CIDR range as the one defined in this file. Currently, the solution is set to be deployed in only two Availability Zones, so the suggestion is to keep the origin_subnet_mask value as is.

To deploy the primary resources:

  1. Download the solution folder from GitHub:
    $ git clone https://github.com/aws-samples/automatically-replicate-your-card-payment-keys.git && cd automatically-replicate-your-card-payment-keys

  2. Inside the solution directory, create a python virtual environment:
    $ python3 -m venv .venv

  3. Activate the python virtual environment:
    $ source .venv/bin/activate

  4. Install the dependencies:
    $ pip install -r requirements.txt

  5. If this is the first time deploying resources with the AWS CDK to your account in the selected AWS Region, run:
    $ cdk bootstrap

  6. Deploy the solution using the AWS CDK:
    $ cdk deploy

    Expected output:

    Do you wish to deploy these changes (y/n)? y  
    apc-crr: deploying... [1/1]  
    apc-crr: creating CloudFormation changeset...
     ✅  apc-crr
    ✨  Deployment time: 307.88s
    Stack ARN:
    arn:aws:cloudformation:<aws_region>:<aws_account>:stack/apc-crr/<stack_id>
    ✨  Total time: 316.06s

  7. If the solution is correctly deployed, an AWS CloudFormation stack with the name apc-crr will have a status of CREATE_COMPLETE status. You can check that by running the following command:
    $ aws cloudformation list-stacks --stack-status CREATE_COMPLETE

    Expected output:

    {
        "StackSummaries": [
            {
                "StackId": "arn:aws:cloudformation:us-east-1:111122223333:stack/apc-crr/5933bc00-f5c1-11ee-9bb2-12ef8d00991b",
                "StackName": "apc-crr",
                "CreationTime": "2024-04-08T16:02:07.413000+00:00",
                "LastUpdatedTime": "2024-04-08T16:02:21.439000+00:00",
                "StackStatus": "CREATE_COMPLETE",
                "DriftInformation": {
                    "StackDriftStatus": "NOT_CHECKED"
                }
            },
            {
                "StackId": "arn:aws:cloudformation:us-east-1:111122223333:stack/CDKToolkit/781e5390-e528-11ee-823a-0a6d63bbc467",
                "StackName": "CDKToolkit",
                "TemplateDescription": "This stack includes resources needed to deploy AWS CDK apps into this environment",
                "CreationTime": "2024-03-18T13:07:27.472000+00:00",
                "LastUpdatedTime": "2024-03-18T13:07:35.060000+00:00",
                "StackStatus": "CREATE_COMPLETE",
                "DriftInformation": {
                    "StackDriftStatus": "NOT_CHECKED"
                }
            }
        ]
    }

Set up cross-Region replication

Some parameters can be configured before initiating the setup. They’re located in the enable-crr.json file in the ./application folder.

The contents of the enable-crr.json file are:

{
  "enabled": true,
  "dest_region": "us-east-1",
  "kek_alias": "CRR_KEK_DO-NOT-DELETE_",
  "key_algo": "TDES_3KEY",
  "kdh_alias": "KDH_SIGN_KEY_DO-NOT-DELETE_",
  "krd_alias": "KRD_SIGN_KEY_DO-NOT-DELETE_",
  "dest_vpc_name": "apc-crr/destination-vpc",
  "dest_vpc_cidr": "10.3.0.0/16",
  "dest_subnet1_cidr": "10.3.0.0/22",
  "dest_subnet2_cidr": "10.3.4.0/22",
  "dest_subnets_prefix_name": "apc-crr/destination-vpc/destination-subnet-private",
  "dest_rt_prefix_name": "apc-crr/destination-vpc/destination-rtb-private"
}

You can change the dest_region, dest_vpc_name, dest_vpc_cidr, dest_subnet1_cidr, dest_subnet2_cidr, dest_subnets_prefix_name and dest_rt_prefix_name parameters.

Validate that there are no VPCs or subnets already created with the same CIDR ranges as are defined in this file.

To enable CRR and monitor its deployment process

  1. Enable CRR.

    From the solution base folder, navigate to the application directory:

    $ cd application

    Run the enable script.

    $ ./enable-crr.sh

    Expected output:

    START RequestId: 8aad062a-ff0b-4963-8ca0-f8078346854f Version: $LATEST  
    Setup has initiated. A CloudFormation template will be deployed in us-west-2.  
    Please check the apcStackMonitor log to follow the deployment status.  
    You can do that by checking the CloudWatch Logs Log group /aws/apc-crr/apcStackMonitor in the Management Console,  
    or by typing on a shell terminal: aws logs tail "/aws/lambda/apcStackMonitor" --follow  
    You can also check the CloudFormation Stack in the Management Console: Account 111122223333, Region us-west-2  
    END RequestId: 8aad062a-ff0b-4963-8ca0-f8078346854f  
    REPORT RequestId: 8aad062a-ff0b-4963-8ca0-f8078346854f  Duration: 1484.53 ms  Billed Duration: 1485 ms  Memory Size: 128 MB Max Memory Used: 79 MB  Init Duration: 400.95 ms

    This will launch a CloudFormation stack to be deployed in the AWS Region that the keys will be replicated to (secondary Region). Logs will be presented in the /aws/lambda/apcStackMonitor log (terminal from step 2).

    If the stack is successfully deployed (CREATE_COMPLETE state), then the KEK setup will be invoked. Logs will be presented in the /aws/lambda/apcKekSetup log (terminal from step 3).

    If the following message is displayed in the apcKekSetup log, then it means that the setup was concluded and new working keys created, deleted, or imported will be replicated.

    Keys Generated, Imported and Deleted in <Primary (Origin) Region> are now being automatically replicated to <Secondary (Destination) Region>

    There should be two keys created in the Region where CRR is deployed and two keys created where the working keys will be replicated. Use the following commands to check the keys:

    $ aws payment-cryptography list-keys --region us-east-1

    Command output showing the keys generated in the primary Region (us-east-1 in the example):

    {
        "Keys": [
            {
                "Enabled": true,
                "KeyArn": "arn:aws:payment-cryptography:us-east-1:111122223333:key/oevdxprw6szesmfx",
                "KeyAttributes": {
                    "KeyAlgorithm": "RSA_4096",
                    "KeyClass": "PUBLIC_KEY",
                    "KeyModesOfUse": {
                        "Decrypt": false,
                        "DeriveKey": false,
                        "Encrypt": false,
                        "Generate": false,
                        "NoRestrictions": false,
                        "Sign": false,
                        "Unwrap": false,
                        "Verify": true,
                        "Wrap": false
                    },
                    "KeyUsage": "TR31_S0_ASYMMETRIC_KEY_FOR_DIGITAL_SIGNATURE"
                },
                "KeyState": "CREATE_COMPLETE"
            },
            {
                "Enabled": true,
                "Exportable": true,
                "KeyArn": "arn:aws:payment-cryptography:us-east-1:111122223333:key/ey63g3an7u4ifz7u",
                "KeyAttributes": {
                    "KeyAlgorithm": "TDES_3KEY",
                    "KeyClass": "SYMMETRIC_KEY",
                    "KeyModesOfUse": {
                        "Decrypt": true,
                        "DeriveKey": false,
                        "Encrypt": true,
                        "Generate": false,
                        "NoRestrictions": false,
                        "Sign": false,
                        "Unwrap": true,
                        "Verify": false,
                        "Wrap": true
                    },
                    "KeyUsage": "TR31_K0_KEY_ENCRYPTION_KEY"
                },
                "KeyCheckValue": "7FB069",
                "KeyState": "CREATE_COMPLETE"
            }
        ]
    }
    
    $ aws payment-cryptography list-keys --region us-west-2

    The following is the command output showing the keys generated in the secondary Region (us-west-2 in the example):

    {
        "Keys": [
            {
                "Enabled": true,
                "Exportable": true,
                "KeyArn": "arn:aws:payment-cryptography:us-west-2:111122223333:key/4luahnz4ubuioq4s",
                "KeyAttributes": {
                    "KeyAlgorithm": "RSA_2048",
                    "KeyClass": "ASYMMETRIC_KEY_PAIR",
                    "KeyModesOfUse": {
                        "Decrypt": true,
                        "DeriveKey": false,
                        "Encrypt": true,
                        "Generate": false,
                        "NoRestrictions": false,
                        "Sign": false,
                        "Unwrap": true,
                        "Verify": false,
                        "Wrap": true
                    },
                    "KeyUsage": "TR31_D1_ASYMMETRIC_KEY_FOR_DATA_ENCRYPTION"
                },
                "KeyCheckValue": "56739D06",
                "KeyState": "CREATE_COMPLETE"
            },
            {
                "Enabled": true,
                "Exportable": true,
                "KeyArn": "arn:aws:payment-cryptography:us-west-2:111122223333:key/5gao3i6qvuyqqtzk",
                "KeyAttributes": {
                    "KeyAlgorithm": "TDES_3KEY",
                    "KeyClass": "SYMMETRIC_KEY",
                    "KeyModesOfUse": {
                        "Decrypt": true,
                        "DeriveKey": false,
                        "Encrypt": true,
                        "Generate": false,
                        "NoRestrictions": false,
                        "Sign": false,
                        "Unwrap": true,
                        "Verify": false,
                        "Wrap": true
                    },
                    "KeyUsage": "TR31_K0_KEY_ENCRYPTION_KEY"
                },
                "KeyCheckValue": "7FB069",
                "KeyState": "CREATE_COMPLETE"
            }
        ]
    }

  2. Monitor the resources deployment in the secondary Region. Open a terminal to tail the apcStackMonitor Lambda log and check the deployment of the resources in the secondary Region.
    $ aws logs tail "/aws/lambda/apcStackMonitor" --follow

    The expected output is:

    2024-03-05T15:18:17.870000+00:00 2024/03/05/apcStackMonitor[$LATEST]6e6762b029cb4f7d8963c3206226deac INIT_START Runtime Version: python:3.11.v29  Runtime Version ARN: arn:aws:lambda:us-east-1::runtime:2fb93380dac14772d30092f109b1784b517398458eef71a3f757425231fe6769  
    2024-03-05T15:18:18.321000+00:00 2024/03/05/apcStackMonitor[$LATEST]6e6762b029cb4f7d8963c3206226deac START RequestId: 1bdd37b4-e95b-43bd-a49b-9da55e603845 Version: $LATEST  
    2024-03-05T15:18:18.933000+00:00 2024/03/05/apcStackMonitor[$LATEST]6e6762b029cb4f7d8963c3206226deac Stack creation in progress. Status: CREATE_IN_PROGRESS  
    2024-03-05T15:18:24.017000+00:00 2024/03/05/apcStackMonitor[$LATEST]6e6762b029cb4f7d8963c3206226deac Stack creation in progress. Status: CREATE_IN_PROGRESS  
    2024-03-05T15:18:29.108000+00:00 2024/03/05/apcStackMonitor[$LATEST]6e6762b029cb4f7d8963c3206226deac Stack creation in progress. Status: CREATE_IN_PROGRESS  
    ...  
    2024-03-05T15:21:32.302000+00:00 2024/03/05/apcStackMonitor[$LATEST]6e6762b029cb4f7d8963c3206226deac Stack creation in progress. Status: CREATE_IN_PROGRESS  
    2024-03-05T15:21:37.390000+00:00 2024/03/05/apcStackMonitor[$LATEST]6e6762b029cb4f7d8963c3206226deac Stack creation completed. Status: CREATE_COMPLETE  
    2024-03-05T15:21:38.258000+00:00 2024/03/05/apcStackMonitor[$LATEST]6e6762b029cb4f7d8963c3206226deac Stack successfully deployed. Status: CREATE_COMPLETE  
    2024-03-05T15:21:38.354000+00:00 2024/03/05/apcStackMonitor[$LATEST]6e6762b029cb4f7d8963c3206226deac END RequestId: 1bdd37b4-e95b-43bd-a49b-9da55e603845  
    2024-03-05T15:21:38.354000+00:00 2024/03/05/apcStackMonitor[$LATEST]6e6762b029cb4f7d8963c3206226deac REPORT RequestId: 1bdd37b4-e95b-43bd-a49b-9da55e603845Duration: 200032.11 ms Billed Duration: 200033 ms  Memory Size: 128 MB Max Memory Used: 93 MB  Init Duration: 450.87 ms

  3. Monitor the setup of the KEKs between the primary and secondary Regions. Open another terminal to tail the apcKekSetup Lambda log and check the setup of the KEK between the key distribution host (Payment Cryptography in the primary Region) and the key receiving devices (Payment Cryptography in the secondary Region).

    This process uses the TR-34 norm.

    $ aws logs tail "/aws/lambda/apcKekSetup" -–follow

    The expected output is:

    2024-03-12T14:58:18.954000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 INIT_START Runtime Version: python:3.11.v29  Runtime Version ARN: arn:aws:lambda:us-west-2::runtime:2fb93380dac14772d30092f109b1784b517398458eef71a3f757425231fe6769  
    2024-03-12T14:58:19.399000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 START RequestId: a9b60171-dfaf-433a-954c-b0a332d22f50 Version: $LATEST  
    2024-03-12T14:58:19.596000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 ##### Step 1. Generating Key Encryption Key (KEK) - Key that will be used to encrypt the Working Keys  
    2024-03-12T14:58:19.850000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 ##### Step 2. Getting APC Import Parameters from us-east-1  
    2024-03-12T14:58:21.680000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 ##### Step 3. Importing the Root Wrapping Certificates in us-west-2  
    2024-03-12T14:58:21.826000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 ##### Step 4. Getting APC Export Parameters from us-west-2  
    2024-03-12T14:58:23.193000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 ##### Step 5. Importing the Root Signing Certificates in us-east-1  
    2024-03-12T14:58:23.439000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 ##### Step 6. Exporting the KEK from us-west-2  
    2024-03-12T14:58:23.555000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 ##### Step 7. Importing the Wrapped KEK to us-east-1  
    2024-03-12T14:58:23.840000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 ##### Initial Key Exchange Successfully Completed.  
    2024-03-12T14:58:23.840000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 Keys Generated, Imported and Deleted in us-west-2 are now being automatically replicated to us-east-1  
    2024-03-12T14:58:23.840000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 Keys already present in APC won't be replicated. If you want to, it must be done manually.  
    2024-03-12T14:58:23.844000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 END RequestId: a9b60171-dfaf-433a-954c-b0a332d22f50  
    2024-03-12T14:58:23.844000+00:00 2024/03/12/apcKekSetup[$LATEST]ea4c6a7c85ac42da8a043aa8626d2897 REPORT RequestId: a9b60171-dfaf-433a-954c-b0a332d22f50 Duration: 4444.78 ms  Billed Duration: 4445 ms  Memory Size: 5120 MB  Max Memory Used: 95 MB  Init Duration: 444.73 ms

Testing

Now it’s time to test the solution. The idea is to simulate an application that manages keys in the service. You will use AWS CLI to send commands directly from a local computer to the Payment Cryptography public endpoints.

Check if the user or role being used has the necessary permissions to manage keys in the service. The following AWS Identity and Access Management (IAM) policy example shows an IAM policy that can be attached to the user or role that will run the commands in the service.

{
      "Version": "2012-10-17",
      "Statement": [
            {
               "Effect": "Allow",
               "Action": [
                  "payment-cryptography:CreateKey",
                  "payment-cryptography:ImportKey",
                  "payment-cryptography:DeleteKey"
               ],
               "Resource": [
                  "*"
               ]
            }   
      ]
   }

Note: As an add-on, you can change the *(asterisk) to the Amazon Resource Name (ARN) of the created key.

For information about IAM policies, see the Identity and access management for Payment Cryptography documentation.

To test the solution

  1. Prepare to monitor the replication processes. Open a new terminal to monitor the apcReplicateWk log and verify that keys are being replicated from one Region to the other.
    $ aws logs tail "/aws/lambda/apcReplicateWk" --follow

  2. Create, import, and delete working keys. Start creating and deleting keys in the account and Region where the CRR solution was deployed (primary Region).

    Currently, the solution only listens to the CreateKey, ImportKey and DeleteKey commands. CreateAlias and DeleteAlias commands aren’t yet implemented, so the aliases won’t replicate.

    It takes some time for the replication function to be invoked because it relies on the following steps:

    1. A Payment Cryptography (CreateKey, ImportKey, or DeleteKey) log event is delivered to a CloudTrail trail.
    2. The log event is sent to the CloudWatch Logs log group, which invokes the subscription filter and the Lambda function associated with it is run.

    CloudTrail typically delivers logs within about 5 minutes of an API call. This time isn’t guaranteed. See the AWS CloudTrail Service Level Agreement for more information.

    Example 1: Create a working key

    Run the following command:

    aws payment-cryptography create-key --exportable --key-attributes KeyAlgorithm=TDES_2KEY,\
    KeyUsage=TR31_C0_CARD_VERIFICATION_KEY,KeyClass=SYMMETRIC_KEY, \
    KeyModesOfUse='{Generate=true,Verify=true}'

    Command output:

    {
        "Key": {
            "CreateTimestamp": "2022-10-26T16:04:11.642000-07:00",
            "Enabled": true,
            "Exportable": true,
            "KeyArn": "arn:aws:payment-cryptography:us-east-1:111122223333:key/hjprdg5o4jtgs5tw",
            "KeyAttributes": {
                "KeyAlgorithm": "TDES_2KEY",
                "KeyClass": "SYMMETRIC_KEY",
                "KeyModesOfUse": {
                    "Decrypt": false,
                    "DeriveKey": false,
                    "Encrypt": false,
                    "Generate": true,
                    "NoRestrictions": false,
                    "Sign": false,
                    "Unwrap": false,
                    "Verify": true,
                    "Wrap": false
                },
                "KeyUsage": "TR31_C0_CARD_VERIFICATION_KEY"
            },
            "KeyCheckValue": "B72F",
            "KeyCheckValueAlgorithm": "ANSI_X9_24",
            "KeyOrigin": "AWS_PAYMENT_CRYPTOGRAPHY",
            "KeyState": "CREATE_COMPLETE",
            "UsageStartTimestamp": "2022-10-26T16:04:11.559000-07:00"
        }
    }

    From the terminal where the /aws/lambda/apcReplicateWk log is being tailed, the expected output is:

    2024-03-05T15:57:13.871000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 INIT_START Runtime Version: python:3.11.v29   Runtime Version ARN: arn:aws:lambda:us-east-1::runtime:2fb93380dac14772d30092f109b1784b517398458eef71a3f757425231fe6769  
    2024-03-05T15:57:14.326000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 START RequestId: c7670e9b-6db0-494e-86c4-4c64126695ee Version: $LATEST  
    2024-03-05T15:57:14.327000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 This is a WK! Sync in progress...  
    2024-03-05T15:57:14.717000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 ##### Step 1. Exporting SYMMETRIC_KEY arn:aws:payment-cryptography:us-east-1:111122223333:key/hjprdg5o4jtgs5tw from us-east-1 using alias/CRR_KEK_DO-NOT-DELETE_6e3606a32690 Key Encryption Key  
    2024-03-05T15:57:15.044000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 ##### Step 2. Importing the Wrapped Key to us-west-2  
    2024-03-05T15:57:15.661000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 Imported SYMMETRIC_KEY key: arn:aws:payment-cryptography:us-west-2:111122223333:key/bykk4cwnbyfu3exo as TR31_C0_CARD_VERIFICATION_KEY in us-west-2  
    2024-03-05T15:57:15.794000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 END RequestId: c7670e9b-6db0-494e-86c4-4c64126695ee  
    2024-03-05T15:57:15.794000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 REPORT RequestId: c7670e9b-6db0-494e-86c4-4c64126695ee        Duration: 1468.13 ms    Billed Duration: 1469 ms        Memory Size: 128 MB     Max Memory Used: 78 MB  Init Duration: 454.02 ms

    Example 2: Delete a working key:

    Run the following command:

    aws payment-cryptography delete-key \
    --key-identifier arn:aws:payment-cryptography:us-east-1:111122223333:key/hjprdg5o4jtgs5tw

    Command output:

    {
        "Key": {
            "KeyArn": "arn:aws:payment-cryptography:us-east-2:111122223333:key/kwapwa6qaifllw2h",
            "KeyAttributes": {
                "KeyUsage": "TR31_C0_CARD_VERIFICATION_KEY",
                "KeyClass": "SYMMETRIC_KEY",
                "KeyAlgorithm": "TDES_2KEY",
                "KeyModesOfUse": {
                    "Encrypt": false,
                    "Decrypt": false,
                    "Wrap": false,
                    "Unwrap": false,
                    "Generate": true,
                    "Sign": false,
                    "Verify": true,
                    "DeriveKey": false,
                    "NoRestrictions": false
                }
            },
            "KeyCheckValue": "",
            "KeyCheckValueAlgorithm": "ANSI_X9_24",
            "Enabled": false,
            "Exportable": true,
            "KeyState": "DELETE_PENDING",
            "KeyOrigin": "AWS_PAYMENT_CRYPTOGRAPHY",
            "CreateTimestamp": "2023-06-05T12:01:29.969000-07:00",
            "UsageStopTimestamp": "2023-06-05T14:31:13.399000-07:00",
            "DeletePendingTimestamp": "2023-06-12T14:58:32.865000-07:00"
        }
    }

    From the terminal where the /aws/lambda/apcReplicateWk log is being tailed, the expected output is:

    2024-03-05T16:02:56.892000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 START RequestId: d557cb28-6974-4888-bb7b-9f8aa4b78640 Version: $LATEST  
    2024-03-05T16:02:56.894000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 This is not CreateKey or ImportKey!  
    2024-03-05T16:02:57.621000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 arn:aws:payment-cryptography:us-west-2: 111122223333:key/bykk4cwnbyfu3exo deleted from us-west-2.  
    2024-03-05T16:02:57.691000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 END RequestId: d557cb28-6974-4888-bb7b-9f8aa4b78640  
    2024-03-05T16:02:57.691000+00:00 2024/03/05/apcReplicateWk[$LATEST]66dae4eef2bf42f6afd0e4cc70b48606 REPORT RequestId: d557cb28-6974-4888-bb7b-9f8aa4b78640        Duration: 802.89 ms     Billed Duration: 803 ms Memory Size: 128 MB     Max Memory Used: 79 MB

    See the service documentation for more information about key management operations.

Clean up

You can disable the solution (keys will stop being replicated, but the resources from the primary Region will remain deployed) or destroy the resources that were deployed.

Note: Completing only Step 3, destroying the stack, won’t delete the resources deployed in the secondary Region or the keys that have been generated.

  1. Disable the CRR solution.

    The KEKs created during the enablement process will be disabled and marked for deletion in both the primary and secondary Regions. The waiting period before deletion is 3 days.

    From the base directory where the solution is deployed, run the following commands:

    $ source .venv/bin/activate
    $ cd application
    $ ./disable-crr.sh

    Expected output:

    START RequestId: bc96659c-3063-460a-8b29-2aa21b967c9a Version: $LATEST  
    Deletion has initiated...  
    Please check the apcKekSetup log to check if the solution has been successfully disabled.  
    You can do that by checking the CloudWatch Logs Log group /aws/apc-crr/apcKekSetup in the Management Console,  
    or by typing on a shell terminal: aws logs tail "/aws/lambda/apcKekSetup" --follow  
      
    Please check the apcStackMonitor log to follow the stack deletion status.  
    You can do that by checking the CloudWatch Logs Log group /aws/apc-crr/apcStackMonitor in the Management Console,  
    or by typing on a shell terminal: aws logs tail "/aws/lambda/apcStackMonitor" --follow  
    END RequestId: bc96659c-3063-460a-8b29-2aa21b967c9a  
    REPORT RequestId: bc96659c-3063-460a-8b29-2aa21b967c9a  Duration: 341.94 ms Billed Duration: 342 ms Memory Size: 128 MB Max Memory Used: 76 MB  Init Duration: 429.87 ms

  2. Monitor the Lambda functions logs.

    Open two other terminals.

    1. On the first terminal, run:
      $ aws logs tail "/aws/lambda/apcKekSetup" --follow

    2. On the second terminal, run:
      $ aws logs tail "/aws/lambda/apcStackMonitor" --follow

    Keys created during the exchange of the KEK will be deleted and the logs will be presented in the /aws/lambda/apcKekSetup log group.

    Expected output:

    2024-03-05T16:40:23.510000+00:00 2024/03/05/apcKekSetup[$LATEST]1c97946d8bc747b19cc35d9b1472ff8d INIT_START Runtime Version: python:3.11.v28  Runtime Version ARN: arn:aws:lambda:us-east-1::runtime:7893bafe1f7e5c0681bc8da889edf656777a53c2a26e3f73436bdcbc87ccfbe8  
    2024-03-05T16:40:23.971000+00:00 2024/03/05/apcKekSetup[$LATEST]1c97946d8bc747b19cc35d9b1472ff8d START RequestId: fc10b303-f028-4a94-a2cf-b8c0a762ea16 Version: $LATEST  
    2024-03-05T16:40:23.971000+00:00 2024/03/05/apcKekSetup[$LATEST]1c97946d8bc747b19cc35d9b1472ff8d Disabling CRR and Deleting KEKs  
    2024-03-05T16:40:25.276000+00:00 2024/03/05/apcKekSetup[$LATEST]1c97946d8bc747b19cc35d9b1472ff8d Keys and aliases deleted from APC.  
    2024-03-05T16:40:25.294000+00:00 2024/03/05/apcKekSetup[$LATEST]1c97946d8bc747b19cc35d9b1472ff8d DB status updated.  
    2024-03-05T16:40:25.297000+00:00 2024/03/05/apcKekSetup[$LATEST]1c97946d8bc747b19cc35d9b1472ff8d END RequestId: fc10b303-f028-4a94-a2cf-b8c0a762ea16  
    2024-03-05T16:40:25.297000+00:00 2024/03/05/apcKekSetup[$LATEST]1c97946d8bc747b19cc35d9b1472ff8d REPORT RequestId: fc10b303-f028-4a94-a2cf-b8c0a762ea16 Duration: 1326.39 ms  Billed Duration: 1327 ms  Memory Size: 5120 MB  Max Memory Used: 94 MB  Init Duration: 460.29 ms

    Second, the CloudFormation stack will be deleted with its associated resources.
    Logs will be presented in the /aws/lambda/apcStackMonitor Log group.

    Expected output:

    2024-03-05T16:40:25.854000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec START RequestId: 6b0b8207-19ae-40a1-b889-c92f8a5c243c Version: $LATEST  
    2024-03-05T16:40:26.486000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec De-provisioning Resources in the Destination Region. StackName: apc-setup-orchestrator-77aecbcf-1e4f-4e2a-8faa-6e3606a32690  
    2024-03-05T16:40:26.805000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec Stack deletion in progress. Status: DELETE_IN_PROGRESS  
    2024-03-05T16:40:31.889000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec Stack deletion in progress. Status: DELETE_IN_PROGRESS  
    2024-03-05T16:40:36.977000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec Stack deletion in progress. Status: DELETE_IN_PROGRESS  
    2024-03-05T16:40:42.065000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec Stack deletion in progress. Status: DELETE_IN_PROGRESS  
    2024-03-05T16:40:47.152000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec Stack deletion in progress. Status: DELETE_IN_PROGRESS  
    ...  
    2024-03-05T16:44:10.598000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec Stack deletion in progress. Status: DELETE_IN_PROGRESS  
    2024-03-05T16:44:15.683000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec Stack deletion in progress. Status: DELETE_IN_PROGRESS  
    2024-03-05T16:44:20.847000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec Stack deletion completed. Status: DELETE_COMPLETE  
    2024-03-05T16:44:21.043000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec Resources successfully deleted. Status: DELETE_COMPLETE  
    2024-03-05T16:44:21.601000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec END RequestId: 6b0b8207-19ae-40a1-b889-c92f8a5c243c  
    2024-03-05T16:44:21.601000+00:00 2024/03/05/apcStackMonitor[$LATEST]2cb4c9044a08474894ff5fa81940dbec REPORT RequestId: 6b0b8207-19ae-40a1-b889-c92f8a5c243cDuration: 235746.42 ms Billed Duration: 235747 ms  Memory Size: 128 MB Max Memory Used: 94 MB

  3. Destroy the CDK stack.
    $ cd ..
    $ cdk destroy

    Expected output:

    Are you sure you want to delete: apc-crr (y/n)? y  
    apc-crr: destroying... [1/1]  
     ✅  apc-crr: destroyed

  4. Delete all remaining working keys from the primary Region. If keys generated in the primary Region weren’t deleted before disabling the solution, then they’ll also exist in the secondary Region. To clean up keys in both Regions, get the key ARNS that have a status of CREATE_COMPLETE and delete them.
    $ aws payment-cryptography list-keys --region <Primary (Origin) Region>
    
    $ aws payment-cryptography delete-key \
    --key-identifier <key arn> --region <Primary (Origin) Region>
    
    $ aws payment-cryptography list-keys --region <Secondary (Destination) Region>
    
    $ aws payment-cryptography delete-key \
    --key-identifier <key arn> --region <Secondary (Destination) Region>

Security considerations

While using this Payment Cryptography CRR solution, it is crucial that you follow security best practices to maintain the highest level of protection for sensitive payment data:

  • Least privilege access: Implement strict access controls and follow the principle of least privilege, granting access to payment cryptography resources only to authorized personnel and services.
  • Encryption in transit and at rest: Make sure that sensitive data, including encryption keys and payment card data, is encrypted both in transit and at rest using industry-standard encryption algorithms.
  • Audit logging and monitoring: Activate audit logging and continuously monitor activity logs for suspicious or unauthorized access attempts.
  • Regular key rotation: Implement a key rotation strategy to periodically rotate encryption keys, reducing the risk of key compromise and minimizing potential exposure.
  • Incident response plan: Develop and regularly test an incident response plan to promote efficient and coordinated actions in the event of a security breach or data compromise.

Conclusion

In the rapidly evolving world of card payment transactions, maintaining high availability, resilience, robust security, and disaster recovery capabilities is crucial for maintaining customer trust and business continuity. AWS Payment Cryptography offers a solution that is tailored specifically for protecting sensitive payment card data.

By using the CRR solution, organizations can confidently address the stringent requirements of the payment industry, safeguarding sensitive data while providing continued access to payment services, even in the face of regional outages or disasters. With Payment Cryptography, organizations are empowered to deliver seamless and secure payment experiences to their customers.

To go further with this solution, you can modify it to fit your organization architecture by, for example, adding replication for the CreateAlias command. This will allow the Payment Cryptography keys alias to also be replicated between the primary and secondary Regions.

References

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Ruy Cavalcanti
Ruy Cavalcanti

Ruy is a Senior Security Architect for the Latin American financial market at AWS. He has worked in IT and Security for over 19 years, helping customers create secure architectures and solve data protection and compliance challenges. When he’s not architecting secure solutions, he enjoys jamming on his guitar, cooking Brazilian-style barbecue, and spending time with his family and friends.

Attribute Amazon EMR on EC2 costs to your end-users

Post Syndicated from Raj Patel original https://aws.amazon.com/blogs/big-data/attribute-amazon-emr-on-ec2-costs-to-your-end-users/

Amazon EMR on EC2 is a managed service that makes it straightforward to run big data processing and analytics workloads on AWS. It simplifies the setup and management of popular open source frameworks like Apache Hadoop and Apache Spark, allowing you to focus on extracting insights from large datasets rather than the underlying infrastructure. With Amazon EMR, you can take advantage of the power of these big data tools to process, analyze, and gain valuable business intelligence from vast amounts of data.

Cost optimization is one of the pillars of the Well-Architected Framework. It focuses on avoiding unnecessary costs, selecting the most appropriate resource types, analyzing spend over time, and scaling in and out to meet business needs without overspending. An optimized workload maximizes the use of all available resources, delivers the desired outcome at the most cost-effective price point, and meets your functional needs.

The current Amazon EMR pricing page shows the estimated cost of the cluster. You can also use AWS Cost Explorer to get more detailed information about your costs. These views give you an overall picture of your Amazon EMR costs. However, you may need to attribute costs at the individual Spark job level. For example, you might want to know the usage cost in Amazon EMR for the finance business unit. Or, for chargeback purposes, you might need to aggregate the cost of Spark applications by functional area. After you have allocated costs to individual Spark jobs, this data can help you make informed decisions to optimize your costs. For instance, you could choose to restructure your applications to utilize fewer resources. Alternatively, you might opt to explore different pricing models like Amazon EMR on EKS or Amazon EMR Serverless.

In this post, we share a chargeback model that you can use to track and allocate the costs of Spark workloads running on Amazon EMR on EC2 clusters. We describe an approach that assigns Amazon EMR costs to different jobs, teams, or lines of business. You can use this feature to distribute costs across various business units. This can assist you in monitoring the return on investment for your Spark-based workloads.

Solution overview

The solution is designed to help you track the cost of your Spark applications running on EMR on EC2. It can help you identify cost optimizations and improve the cost-efficiency of your EMR clusters.

The proposed solution uses a scheduled AWS Lambda function that operates on a daily basis. The function captures usage and cost metrics, which are subsequently stored in Amazon Relational Database Service (Amazon RDS) tables. The data stored in the RDS tables is then queried to derive chargeback figures and generate reporting trends using Amazon QuickSight. The utilization of these AWS services incurs additional costs for implementing this solution. Alternatively, you can consider an approach that involves a cron-based agent script installed on your existing EMR cluster, if you want to avoid the use of additional AWS services and associated costs for building your chargeback solution. This script stores the relevant metrics in an Amazon Simple Storage Service (Amazon S3) bucket, and uses Python Jupyter notebooks to generate chargeback numbers based on the data files stored in Amazon S3, using AWS Glue tables.

The following diagram shows the current solution architecture.

Solution Architecture

The workflow consists of the following steps:

  1. A Lambda function gets the following parameters from Parameter Store, a capability of AWS Systems Manager:
    {
      "yarn_url": "http://dummy.compute-1.amazonaws.com:8088/ws/v1/cluster/apps",
      "tbl_applicationlogs_lz": "public.emr_applications_execution_log_lz",
      "tbl_applicationlogs": "public.emr_applications_execution_log",
      "tbl_emrcost": "public.emr_cluster_usage_cost",
      "tbl_emrinstance_usage": "public.emr_cluster_instances_usage",
      "emrcluster_id": "j-xxxxxxxxxx",
      "emrcluster_name": "EMR_Cost_Measure",
      "emrcluster_role": "dt-dna-shared",
      "emrcluster_linkedaccount": "xxxxxxxxxxx",
      "postgres_rds": {
        "host": "xxxxxxxxx.amazonaws.com",
        "dbname": "postgres",
        "user": "postgresadmin",
        "secretid": "postgressecretid"
      }
    }

  2. The Lambda function extracts Spark application run logs from the EMR cluster using the Resource Manager API. The following metrics are extracted as part of the process: vcore-seconds, memory MB-seconds, and storage GB-seconds.
  3. The Lambda function captures the daily cost of EMR clusters from Cost Explorer.
  4. The Lambda function also extracts EMR On-Demand and Spot Instance usage data using the Amazon Elastic Compute Cloud (Amazon EC2) Boto3 APIs.
  5. Lambda function loads these datasets into an RDS database.
  6. The cost of running a Spark application is determined by the amount of CPU resources it uses, compared to the total CPU usage of all Spark applications. This information is used to distribute the overall cost among different teams, business lines, or EMR queues.

The extraction process runs daily, extracting the previous day’s data and storing it in an Amazon RDS for PostgreSQL table. The historical data in the table needs to be purged based on your use case.

The solution is open source and available on GitHub.

You can use the AWS Cloud Development Kit (AWS CDK) to deploy the Lambda function, RDS for PostgreSQL data model tables, and a QuickSight dashboard to track EMR cluster cost at the job, team, or business unit level.

The following schema show the tables used in the solution which are queried by QuickSight to populate the dashboard.

  • emr_applications_execution_log_lz or public.emr_applications_execution_log – Storage for daily run metrics for all jobs run on the EMR cluster:
    • appdatecollect – Log collection date
    • app_id – Spark job run ID
    • app_name – Run name
    • queue – EMR queue in which job was run
    • job_state – Job running state
    • job_status – Job run final status (Succeeded or Failed)
    • starttime – Job start time
    • endtime – Job end time
    • runtime_seconds – Runtime in seconds
    • vcore_seconds – Consumed vCore CPU in seconds
    • memory_seconds – Memory consumed
    • running_containers – Containers used
    • rm_clusterid – EMR cluster ID
  • emr_cluster_usage_cost – Captures Amazon EMR and Amazon EC2 daily cost consumption from Cost Explorer and loads the data into the RDS table:
    • costdatecollect – Cost collection date
    • startdate – Cost start date
    • enddate – Cost end date
    • emr_unique_tag – EMR cluster associated tag
    • net_unblendedcost – Total unblended daily dollar cost
    • unblendedcost – Total unblended daily dollar cost
    • cost_type – Daily cost
    • service_name – AWS service for which the cost incurred (Amazon EMR and Amazon EC2)
    • emr_clusterid – EMR cluster ID
    • emr_clustername – EMR cluster name
    • loadtime – Table load date/time
  • emr_cluster_instances_usage – Captures the aggregated resource usage (vCores) and allocated resources for each EMR cluster node, and helps identify the idle time of the cluster:
    • instancedatecollect – Instance usage collect date
    • emr_instance_day_run_seconds – EMR instance active seconds in the day
    • emr_region – EMR cluster AWS Region
    • emr_clusterid – EMR cluster ID
    • emr_clustername – EMR cluster name
    • emr_cluster_fleet_type – EMR cluster fleet type
    • emr_node_type – Instance node type
    • emr_market – Market type (on-demand or provisioned)
    • emr_instance_type – Instance size
    • emr_ec2_instance_id – Corresponding EC2 instance ID
    • emr_ec2_status – Running status
    • emr_ec2_default_vcpus – Allocated vCPU
    • emr_ec2_memory – EC2 instance memory
    • emr_ec2_creation_datetime – EC2 instance creation date/time
    • emr_ec2_end_datetime – EC2 instance end date/time
    • emr_ec2_ready_datetime – EC2 instance ready date/time
    • loadtime – Table load date/time

Prerequisites

You must have the following prerequisites before implementing the solution:

  • An EMR on EC2 cluster.
  • The EMR cluster must have a unique tag value defined. You can assign the tag directly on the Amazon EMR console or using Tag Editor. The recommended tag key is cost-center along with a unique value for your EMR cluster. After you create and apply user-defined tags, it can take up to 24 hours for the tag keys to appear on your cost allocation tags page for activation
  • Activate the tag in AWS Billing. It takes about 24 hours to activate the tag if not done before. To activate the tag, follow these steps:
    • On the AWS Billing and Cost Management console, choose Cost allocation tags from navigation pane.
    • Select the tag key that you want to activate.
    • Choose Activate.
  • The Spark application’s name should follow the standardized naming convention. It consists of seven components separated by underscores: <business_unit>_<program>_<application>_<source>_<job_name>_<frequency>_<job_type>. These components are used to summarize the resource consumption and cost in the final report. For example: HR_PAYROLL_PS_PSPROD_TAXDUDUCTION_DLY_LD, FIN_CASHRECEIPT_GL_GLDB_MAIN_DLY_LD, or MKT_CAMPAIGN_CRM_CRMDB_TOPRATEDCAMPAIGN_DLY_LD. The application name must be supplied with the spark submit command using the --name parameter with the standardized naming convention. If any of these components don’t have a value, hardcode the values with the following suggested names:
    • frequency
    • job_type
    • Business_unit
  • The Lambda function should be able to connect to Cost Explorer, connect to the EMR cluster through the Resource Manager APIs, and load data into the RDS for PostgreSQL database. To do this, you need to configure the Lambda function as follows:
    • VPC configuration – The Lambda function should be able to access the EMR cluster, Cost Explorer, AWS Secrets Manager, and Parameter Store. If access is not in place already, you can do this by creating a virtual private cloud (VPC) that includes the EMR cluster and create VPC endpoint for Parameter Store and Secrets Manager and attach it to the VPC. Because there is no VPC endpoint available for Cost Explorer and in order to have Lambda connect to Cost Explorer, a private subnet and a route table are required to send VPC traffic to public NAT gateway. If your EMR cluster is in public subnet, you must create a private subnet including a custom route table and a public NAT gateway, which will allow the Cost Explorer connection to flow from the VPC private subnet. Refer to How do I set up a NAT gateway for a private subnet in Amazon VPC? for setup instructions and attach the newly created private subnet to the Lambda function explicitly.
    • IAM role – The Lambda function needs to have an AWS Identity and Access Management (IAM) role with the following permissions: AmazonEC2ReadOnlyAccess, AWSCostExplorerFullAccess, and AmazonRDSDataFullAccess. This role will be created automatically during AWS CDK stack deployment; you don’t need to set it up separately.
  • The AWS CDK should be installed on AWS Cloud9 (preferred) or another development environment such as VSCode or Pycharm. For more information, refer to Prerequisites.
  • The RDS for PostgreSQL database (v10 or higher) credentials should be stored in Secrets Manager. For more information, refer to Storing database credentials in AWS Secrets Manager.

Create RDS tables

Create the data model tables mentioned in emr-cost-rds-tables-ddl.sql by logging in to postgres rds manually into the public schema.

Use DBeaver or any compatible SQL clients to connect to the RDS instance and validate the tables have been created.

Deploy AWS CDK stacks

Complete the steps in this section to deploy the following resources using the AWS CDK:

  • Parameter Store to store required parameter values
  • IAM role for the Lambda function to help connect to Amazon EMR and underlying EC2 instances, Cost Explorer, CloudWatch, and Parameter Store
  • Lambda function
  1. Clone the GitHub repo:
    git clone [email protected]:aws-samples/attribute-amazon-emr-costs-to-your-end-users.git

  2. Update the following the environment parameters in cdk.context.json (this file can be found in the main directory):
    1. yarn_url – YARN ResourceManager URL to read job run logs and metrics. This URL should be accessible within the VPC where Lambda would be deployed.
    2. tbl_applicationlogs_lz – RDS temp table to store EMR application run logs.
    3. tbl_applicationlogs – RDS table to store EMR application run logs.
    4. tbl_emrcost – RDS table to capture daily EMR cluster usage cost.
    5. tbl_emrinstance_usage – RDS table to store EMR cluster instance usage info.
    6. emrcluster_id – EMR cluster instance ID.
    7. emrcluster_name – EMR cluster name.
    8. emrcluster_tag – Tag key assigned to EMR cluster.
    9. emrcluster_tag_value – Unique value for EMR cluster tag.
    10. emrcluster_role – Service role for Amazon EMR (EMR role).
    11. emrcluster_linkedaccount – Account ID under which the EMR cluster is running.
    12. postgres_rds – RDS for PostgreSQL connection details.
    13. vpc_id – VPC ID in which the EMR cluster is configured and the cost metering Lambda function would be deployed.
    14. vpc_subnets – Comma-separated private subnets ID associated with the VPC.
    15. sg_id – EMR security group ID.

The following is a sample cdk.context.json file after being populated with the parameters:

{
  "yarn_url": "http://dummy.compute-1.amazonaws.com:8088/ws/v1/cluster/apps",
  "tbl_applicationlogs_lz": "public.emr_applications_execution_log_lz",
  "tbl_applicationlogs": "public.emr_applications_execution_log",
  "tbl_emrcost": "public.emr_cluster_usage_cost",
  "tbl_emrinstance_usage": "public.emr_cluster_instances_usage",
  "emrcluster_id": "j-xxxxxxxxxx",
  "emrcluster_name": "EMRClusterName",
  "emrcluster_tag": "EMRClusterTag",
  "emrcluster_tag_value": "EMRClusterUniqueTagValue",
  "emrcluster_role": "EMRClusterServiceRole",
  "emrcluster_linkedaccount": "xxxxxxxxxxx",
  "postgres_rds": {
    "host": "xxxxxxxxx.amazonaws.com",
    "dbname": "dbname",
    "user": "username",
    "secretid": "DatabaseUserSecretID"
  },
  "vpc_id": "xxxxxxxxx",
  "vpc_subnets": "subnet-xxxxxxxxxxx",
  "sg_id": "xxxxxxxxxx"
}

You can choose to deploy the AWS CDK stack using AWS Cloud9 or any other development environment according to your needs. For instructions to set up AWS Cloud9, refer to Getting started: basic tutorials for AWS Cloud9.

  1. Go to AWS Cloud9 and choose File and Upload local files upload the project folder.
  2. Deploy the AWS CDK stack with the following code:
    cd attribute-amazon-emr-costs-to-your-end-users/
    pip install -r requirements.txt
    cdk deploy –-all

The deployed Lambda function requires two external libraries: psycopg2 and requests. The corresponding layer needs to be created and assigned to the Lambda function. For instructions to create a Lambda layer for the requests module, refer to Step-by-Step Guide to Creating an AWS Lambda Function Layer.

Creation of the psycopg2 package and layer is tied to the Python runtime version of the Lambda function. Provided that the Lambda function uses the Python 3.9 runtime, complete the following steps to create the corresponding layer package for peycopog2:

  1. Download psycopg2_binary-2.9.9-cp39-cp39-manylinux_2_17_x86_64.manylinux2014_x86_64.whl from https://pypi.org/project/psycopg2-binary/#files.
  2. Unzip and move the contents to a directory named python:
    zip ‘python’ directory

  3. Create a Lambda layer for psycopg2 using the zip file.
  4. Assign the layer to the Lambda function by choosing Add a layer in the deployed function properties.
  5. Validate the AWS CDK deployment.

Your Lambda function details should look similar to the following screenshot.

Lambda Function Screenshot

On the Systems Manager console, validate the Parameter Store content for actual values.

The IAM role details should look similar to the following code, which allows the Lambda function access to Amazon EMR and underlying EC2 instances, Cost Explorer, CloudWatch, Secrets Manager, and Parameter Store:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Action": [
        "ce:GetCostAndUsage",
        "ce:ListCostAllocationTags",
        "ec2:AttachNetworkInterface",
        "ec2:CreateNetworkInterface",
        "ec2:DeleteNetworkInterface",
        "ec2:DescribeInstanceTypes",
        "ec2:DescribeInstances",
        "ec2:DescribeNetworkInterfaces",
        "elasticmapreduce:Describe*",
        "elasticmapreduce:List*",
        "ssm:Describe*",
        "ssm:Get*",
        "ssm:List*"
      ],
      "Resource": "*",
      "Effect": "Allow"
    },
    {
      "Action": [
        "logs:CreateLogGroup",
        "logs:CreateLogStream",
        "logs:DescribeLogStreams",
        "logs:PutLogEvents"
      ],
      "Resource": "arn:aws:logs:*:*:*",
      "Effect": "Allow"
    },
    {
      "Action": "secretsmanager:GetSecretValue",
      "Resource": "arn:aws:secretsmanager:*:*:*",
      "Effect": "Allow"
    }
  ]
}

Test the solution

To test the solution, you can run a Spark job that combines multiple files in the EMR cluster, and you can do this by creating separate steps within the cluster. Refer to Optimize Amazon EMR costs for legacy and Spark workloads for more details on how to add the jobs as steps to EMR cluster.

  1. Use the following sample command to submit the Spark job (emr_union_job.py).
    It takes in three arguments:

    1. <input_full_path> – The Amazon S3 location of the data file that is read in by the Spark job. The path should not be changed. The input_full_path is s3://aws-blogs-artifacts-public/artifacts/BDB-2997/sample-data/input/part-00000-a0885743-e0cb-48b1-bc2b-05eb748ab898-c000.snappy.parquet
    2. <output_path> – The S3 folder where the results are written to.
    3. <number of copies to be unioned> – By changing the input to the Spark job, you can make sure the job runs for different amounts of time and also change the number of Spot nodes used.
spark-submit --deploy-mode cluster --name HR_PAYROLL_PS_PSPROD_TAXDUDUCTION_DLY_LD s3://aws-blogs-artifacts-public/artifacts/BDB-2997/scripts/emr_union_job.py s3://aws-blogs-artifacts-public/artifacts/BDB-2997/sample-data/input/part-00000-a0885743-e0cb-48b1-bc2b-05eb748ab898-c000.snappy.parquet s3://<output_bucket>/<output_path>/ 6

spark-submit --deploy-mode cluster --name FIN_CASHRECEIPT_GL_GLDB_MAIN_DLY_LD s3://aws-blogs-artifacts-public/artifacts/BDB-2997/scripts/emr_union_job.py s3://aws-blogs-artifacts-public/artifacts/BDB-2997/sample-data/input/part-00000-a0885743-e0cb-48b1-bc2b-05eb748ab898-c000.snappy.parquet s3://<output_bucket>/<output_path>/ 12

The following screenshot shows the log of the steps run on the Amazon EMR console.

EMR Steps Execution

  1. Run the deployed Lambda function from the Lambda console. This loads the daily application log, EMR dollar usage, and EMR instance usage details into their respective RDS tables.

The following screenshot of the Amazon RDS query editor shows the results for public.emr_applications_execution_log.

public.emr_applications_execution_log

The following screenshot shows the results for public.emr_cluster_usage_cost.

public.emr_cluster_usage_cost

The following screenshot shows the results for public.emr_cluster_instances_usage.

public.emr_cluster_instances_usage

Cost can be calculated using the preceding three tables based on your requirements. In the following SQL query, you calculate the cost based on relative usage of all applications in a day. You first identify the total vcore-seconds CPU consumed in a day and then find out the percentage share of an application. This drives the cost based on overall cluster cost in a day.

Consider the following example scenario, where 10 applications ran on the cluster for a given day. You would use the following sequence of steps to calculate the chargeback cost:

  1. Calculate the relative percentage usage of each application (consumed vcore-seconds CPU by app/total vcore-seconds CPU consumed).
  2. Now you have the relative resource consumption of each application, distribute the cluster cost to each application. Let’s assume that the total EMR cluster cost for that date is $400.
app_id app_name runtime_seconds vcore_seconds % Relative Usage Amazon EMR Cost ($)
application_00001 app1 10 120 5% 19.83
application_00002 app2 5 60 2% 9.91
application_00003 app3 4 45 2% 7.43
application_00004 app4 70 840 35% 138.79
application_00005 app5 21 300 12% 49.57
application_00006 app6 4 48 2% 7.93
application_00007 app7 12 150 6% 24.78
application_00008 app8 52 620 26% 102.44
application_00009 app9 12 130 5% 21.48
application_00010 app10 9 108 4% 17.84

A sample chargeback cost calculation SQL query is available on the GitHub repo.

You can use the SQL query to create a report dashboard to plot multiple charts for the insights. The following are two examples created using QuickSight.

The following is a daily bar chart.

Cost Daily Bar Chart

The following shows total dollars consumed.

Cost Pie chart

Solution cost

Let’s assume we’re calculating for an environment that runs 1,000 jobs daily, and we run this solution daily:

  • Lambda costs – One run requires 30 Lambda function invocations per month.
  • Amazon RDS cost – The total number of records in the public.emr_applications_execution_log table for a 30-day month would be 30,000 records, which translates to 5.72 MB of storage. If we consider the other two smaller tables and storage overhead, the overall monthly storage requirement would be approximately 12 MB.

In summary, the solution cost according to the AWS Pricing Calculator is $34.20/year, which is negligible.

Clean up

To avoid ongoing charges for the resources that you created, complete the following steps:

  • Delete the AWS CDK stacks:
    cdk destroy –-all

  • Delete the QuickSight report and dashboard, if created.
  • Run the following SQL to drop the tables:
    drop table public.emr_applications_execution_log_lz;
    drop table public.emr_applications_execution_log;
    drop table public.emr_cluster_usage_cost;
    drop table public.emr_cluster_instances_usage;

Conclusion

With this solution, you can deploy a chargeback model to attribute costs to users and groups using the EMR cluster. You can also identify options for optimization, scaling, and separation of workloads to different clusters based on usage and growth needs.

You can collect the metrics for a longer duration to observe trends on the usage of Amazon EMR resources and use that for forecasting purposes.

If you have any thoughts or questions, leave them in the comments section.


About the Authors

Raj Patel is AWS Lead Consultant for Data Analytics solutions based out of India. He specializes in building and modernising analytical solutions. His background is in data warehouse/data lake – architecture, development and administration. He is in data and analytical field for over 14 years.

Ramesh DPRamesh Raghupathy is a Senior Data Architect with WWCO ProServe at AWS. He works with AWS customers to architect, deploy, and migrate to data warehouses and data lakes on the AWS Cloud. While not at work, Ramesh enjoys traveling, spending time with family, and yoga.

Gaurav JainGaurav Jain is a Sr Data Architect with AWS Professional Services, specialized in big data and helps customers modernize their data platforms on the cloud. He is passionate about building the right analytics solutions to gain timely insights and make critical business decisions. Outside of work, he loves to spend time with his family and likes watching movies and sports.

Dipal Mahajan is a Lead Consultant with Amazon Web Services based out of India, where he guides global customers to build highly secure, scalable, reliable, and cost-efficient applications on the cloud. He brings extensive experience on Software Development, Architecture and Analytics from industries like finance, telecom, retail and healthcare.

Copy and mask PII between Amazon RDS databases using visual ETL jobs in AWS Glue Studio

Post Syndicated from Monica Alcalde Angel original https://aws.amazon.com/blogs/big-data/copy-and-mask-pii-between-amazon-rds-databases-using-visual-etl-jobs-in-aws-glue-studio/

Moving and transforming data between databases is a common need for many organizations. Duplicating data from a production database to a lower or lateral environment and masking personally identifiable information (PII) to comply with regulations enables development, testing, and reporting without impacting critical systems or exposing sensitive customer data. However, manually anonymizing cloned information can be taxing for security and database teams.

You can use AWS Glue Studio to set up data replication and mask PII with no coding required. AWS Glue Studio visual editor provides a low-code graphic environment to build, run, and monitor extract, transform, and load (ETL) scripts. Behind the scenes, AWS Glue handles underlying resource provisioning, job monitoring, and retries. There’s no infrastructure to manage, so you can focus on rapidly building compliant data flows between key systems.

In this post, I’ll walk you through how to copy data from one Amazon Relational Database Service (Amazon RDS) for PostgreSQL database to another, while scrubbing PII along the way using AWS Glue. You will learn how to prepare a multi-account environment to access the databases from AWS Glue, and how to model an ETL data flow that automatically masks PII as part of the transfer process, so that no sensitive information will be copied to the target database in its original form. By the end, you’ll be able to rapidly build data movement pipelines between data sources and targets, that can hide PII in order to protect individual identities, without needing to write code.

Solution overview

The following diagram illustrates the solution architecture:
High-level architecture overview

The solution uses AWS Glue as an ETL engine to extract data from the source Amazon RDS database. Built-in data transformations then scrub columns containing PII using pre-defined masking functions. Finally, the AWS Glue ETL job inserts privacy-protected data into the target Amazon RDS database.

This solution employs multiple AWS accounts. Having multi-account environments is an AWS best practice to help isolate and manage your applications and data. The AWS Glue account shown in the diagram is a dedicated account that facilitates the creation and management of all necessary AWS Glue resources. This solution works across a broad array of connections that AWS Glue supports, so you can centralize the orchestration in one dedicated AWS account.

It is important to highlight the following notes about this solution:

  1. Following AWS best practices, the three AWS accounts discussed are part of an organization, but this is not mandatory for this solution to work.
  2. This solution is suitable for use cases that don’t require real-time replication and can run on a schedule or be initiated through events.

Walkthrough

To implement this solution, this guide walks you through the following steps:

  1. Enable connectivity from the AWS Glue account to the source and target accounts
  2. Create AWS Glue components for the ETL job
  3. Create and run the AWS Glue ETL job
  4. Verify results

Prerequisites

For this walkthrough, we’re using Amazon RDS for PostgreSQL 13.14-R1. Note that the solution will work with other versions and database engines that support the same JDBC driver versions as AWS Glue. See JDBC connections for further details.

To follow along with this post, you should have the following prerequisites:

  • Three AWS accounts as follows:
    1. Source account: Hosts the source Amazon RDS for PostgreSQL database. The database contains a table with sensitive information and resides within a private subnet. For future reference, record the associated virtual private cloud (VPC) ID, security group, and private subnets associated to the Amazon RDS database.
    2. Target account: Contains the target Amazon RDS for PostgreSQL database, with the same table structure as the source table, initially empty. The database resides within a private subnet. Similarly, write down the associated VPC ID, security group ID and private subnets.
    3. AWS Glue account: This dedicated account holds a VPC, a private subnet, and a security group. As mentioned in the AWS Glue documentation, the security group includes a self-referencing inbound rule for All TCP and TCP ports (0-65535) to allow AWS Glue to communicate with its components.

The following figure shows a self-referencing inbound rule needed on the AWS Glue account security group.
Self-referencing inbound rule needed on AWS Glue account’s security group

  • Make sure the three VPC CIDRs do not overlap with each other, as shown in the following table:
 VPC Private subnet
Source account   10.2.0.0/16 10.2.10.0/24
AWS Glue account   10.1.0.0/16 10.1.10.0/24
Target account   10.3.0.0/16 10.3.10.0/24

The following diagram illustrates the environment with all prerequisites:
Environment with all prerequisites

To streamline the process of setting up the prerequisites, you can follow the directions in the README file on this GitHub repository.

Database tables

For this example, both source and target databases contain a customer table with the exact same structure. The former is prepopulated with data as shown in the following figure:
Source database customer table pre-populated with data.

The AWS Glue ETL job you will create focuses on masking sensitive information within specific columns. These are last_name, email, phone_number, ssn and notes.

If you want to use the same table structure and data, the SQL statements are provided in the GitHub repository.

Step 1 – Enable connectivity from the AWS Glue account to the source and target accounts

When creating an AWS Glue ETL job, provide the AWS IAM role, VPC ID, subnet ID, and security groups needed for AWS Glue to access the JDBC databases. See AWS Glue: How it works for further details.

In our example, the role, groups, and other information are in the dedicated AWS Glue account. However, for AWS Glue to connect to the databases, you need to enable access to source and target databases from your AWS Glue account’s subnet and security group.

To enable access, first you inter-connect the VPCs. This can be done using VPC peering or AWS Transit Gateway. For this example, we use VPC peering. Alternatively, you can use an S3 bucket as an intermediary storage location. See Setting up network access to data stores for further details.

Follow these steps:

  1. Peer AWS Glue account VPC with the database VPCs
  2. Update the route tables
  3. Update the database security groups

Peer AWS Glue account VPC with database VPCs

Complete the following steps in the AWS VPC console:

  1. On the AWS Glue account, create two VPC peering connections as described in Create VPC peering connection, one for the source account VPC, and one for the target account VPC.
  2. On the source account, accept the VPC peering request. For instructions, see Accept VPC peering connection
  3. On the target account, accept the VPC peering request as well.
  4. On the AWS Glue account, enable DNS Settings on each peering connection. This allows AWS Glue to resolve the private IP address of your databases. For instructions, follow Enable DNS resolution for VPC peering connection.

After completing the preceding steps, the list of peering connections on the AWS Glue account should look like the following figure:
List of VPC peering connections on the AWS Glue account.Note that source and target account VPCs are not peered together. Connectivity between the two accounts isn’t needed.

Update subnet route tables

This step will enable traffic from the AWS Glue account VPC to the VPC subnets associate to the databases in the source and target accounts.

Complete the following steps in the AWS VPC console:

  1. On the AWS Glue account’s route table, for each VPC peering connection, add one route to each private subnet associated to the database. These routes enable AWS Glue to establish a connection to the databases and limit traffic from the AWS Glue account to only the subnets associated to the databases.
  2. On the source account’s route table of the private subnets associated to the database, add one route for the VPC peering with the AWS Glue account. This route will allow traffic back to the AWS Glue account.
  3. Repeat step 2 on the target account’s route table.

For instructions on how to update route tables, see Work with route tables.

Update database security groups

This step is required to allow traffic from the AWS Glue account’s security group to the source and target security groups associated to the databases.

For instructions on how to update security groups, see Work with security groups.

Complete the following steps in the AWS VPC console:

  1. On the source account’s database security group, add an inbound rule with Type PostgreSQL and Source, the AWS Glue account security group.
  2. Repeat step 1 from the target account’s database security group.

The following diagram shows the environment with connectivity enabled from the AWS Glue account to the source and target accounts:Environment with connectivity across accounts enabled.

Step 2 – Create AWS Glue components for the ETL job

The next task is to create the AWS Glue components to synchronize the source and target database schemas with the AWS Glue Data Catalog.

Follow these steps:

  1. Create an AWS Glue Connection for each Amazon RDS database.
  2. Create AWS Glue Crawlers to populate the Data Catalog.
  3. Run the crawlers.

Create AWS Glue connections

Connections enable AWS Glue to access your databases. The main benefit of creating AWS Glue connections is that connections save time by not making you have to specify all connection details every time you create a job. You can then reuse connections when creating jobs in AWS Glue Studio without having to manually enter connection details each time. This makes the job creation process more consistent and faster.

Complete these steps on the AWS Glue account:

  1. On the AWS Glue console, choose the Data connections link on the navigation pane.
  2. Choose Create connection and follow the instructions in the Create connection wizard:
    1. In Choose data source, choose JDBC as data source.
    2. In Configure connection:
      • For JDBC URL, enter the JDBC URL for the source database. For PostgreSQL, the syntax is:
        jdbc:postgresql://database-endpoint:5432/database-name

        You can find the database-endpoint on the Amazon RDS console on the source account.

      • Expand Network options. For VPC, Subnet and Security group, select the ones in the centralized AWS Glue account, as shown in the following figure:
        Network settings (VPC, subnet and security group) for the AWS Glue connection.
    3. In Set Properties, for Name enter Source DB connection-Postgresql.
  3. Repeat steps 1 and 2 to create the connection to the target Amazon RDS database. Name the connection Target DB connection-Postgresql.

Now you have two connections, one for each Amazon RDS database.

Create AWS Glue crawlers

AWS Glue crawlers allow you to automate data discovery and cataloging from data sources and targets. Crawlers explore data stores and auto-generate metadata to populate the Data Catalog, registering discovered tables in the Data Catalog. This helps you to discover and work with the data to build ETL jobs.

To create a crawler for each Amazon RDS database, complete the following steps on the AWS Glue account:

  1. On the AWS Glue console, choose Crawlers in the navigation pane.
  2. Choose Create crawler and follow the instructions in the Add crawler wizard:
    1. In Set crawler properties, for Name enter Source PostgreSQL database crawler.
    2. In Chose data sources and classifiers, choose Not yet.
    3. In Add data source, for Data source choose JDBC, as shown in the following figure:
      AWS Glue crawler JDBC data source settings.
    4. For Connection, choose Source DB Connection - Postgresql.
    5. For Include path, enter the path of your database including the schema. For our example, the path is sourcedb/cx/% where sourcedb is the name of the database, and cx the schema with the customer table.
    6. In Configure security settings, choose the AWS IAM service role created a part of the prerequisites.
    7. In Set output and scheduling, since we don’t have a database yet in the Data Catalog to store the source database metadata, choose Add database and create a database named sourcedb-postgresql.
  3. Repeat steps 1 and 2 to create a crawler for the target database:
    1. In Set crawler properties, for Name enter Target PostgreSQL database crawler.
    2. In Add data source, for Connection, choose Target DB Connection-Postgresql, and for Include path enter targetdb/cx/%.
    3. In Add database, for Name enter targetdb-postgresql.

Now you have two crawlers, one for each Amazon RDS database, as shown in the following figure:List of crawlers created.

Run the crawlers

Next, run the crawlers. When you run a crawler, the crawler connects to the designated data store and automatically populates the Data Catalog with metadata table definitions (columns, data types, partitions, and so on). This saves time over manually defining schemas.

From the Crawlers list, select both Source PostgreSQL database crawler and Target PostgreSQL database crawler, and choose Run.

When finished, each crawler creates a table in the Data Catalog. These tables are the metadata representation of the customer tables.

You now have all the resources to start creating AWS Glue ETL jobs!

Step 3 – Create and run the AWS Glue ETL Job

The proposed ETL job runs four tasks:

  1. Source data extraction – Establishes a connection to the Amazon RDS source database and extracts the data to replicate.
  2. PII detection and scrubbing.
  3. Data transformation – Adjusts and removes unnecessary fields.
  4. Target data loading – Establishes a connection to the target Amazon RDS database and inserts data with masked PII.

Let’s jump into AWS Glue Studio to create the AWS Glue ETL job.

  1. Sign in to the AWS Glue console with your AWS Glue account.
  2. Choose ETL jobs in the navigation pane.
  3. Choose Visual ETL as shown in the following figure:

Entry point to AWS Glue Studio visual interface

Task 1 – Source data extraction

Add a node to connect to the Amazon RDS source database:

  1. Choose AWS Glue Data Catalog from the Sources. This adds a data source node to the canvas.
  2. On the Data source properties panel, select sourcedb-postgresql database and source_cx_customer table from the Data Catalog as shown in the following figure:

Highlights AWS Glue Data Catalog data source node on the left hand side, and the data source node properties on the right hand side.

Task 2 – PII detection and scrubbing

To detect and mask PII, select Detect Sensitive Data node from the Transforms tab.

Let’s take a deeper look into the Transform options on the properties panel for the Detect Sensitive Data node:

  1. First, you can choose how you want the data to be scanned. You can select Find sensitive data in each row or Find columns that contain sensitive data as shown in the following figure. Choosing the former scans all rows for comprehensive PII identification, while the latter scans a sample for PII location at lower cost.

Find sensitive data in each row option selected to detect sensitive data.

Selecting Find sensitive data in each row allows you to specify fine-grained action overrides. If you know your data, with fine-grained actions you can exclude certain columns from detection. You can also customize the entities to detect for every column in your dataset and skip entities that you know aren’t in specific columns. This allows your jobs to be more performant by eliminating unnecessary detection calls for those entities and perform actions unique to each column and entity combination.

In our example, we know our data and we want to apply fine-grained actions to specific columns, so let’s select Find sensitive data in each row. We’ll explore fine-grained actions further below.

  1. Next, you select the types of sensitive information to detect. Take some time to explore the three different options.

In our example, again because we know the data, let’s select Select specific patterns. For Selected patterns, choose Person’s name, Email Address, Credit Card, Social Security Number (SSN) and US Phone as shown in the following figure. Note that some patterns, such as SSNs, apply specifically to the United States and might not detect PII data for other countries. But there are available categories applicable to other countries, and you can also use regular expressions in AWS Glue Studio to create detection entities to help meet your needs.

Patterns selected for detecting PII data

  1. Next, select the level of detection sensitivity. Leave the default value (High).
  2. Next, choose the global action to take on detected entities. Select REDACT and enter **** as the Redaction Text.
  3. Next, you can specify fine-grained actions (overrides). Overrides are optional, but in our example, we want to exclude certain columns from detection, scan certain PII entity types on specific columns only, and specify different redaction text settings for different entity types.

Choose Add to specify the fine-grained action for each entity as shown in the following figure:List of fine-grained actions created. The screenshot includes an arrow pointing to the Add button.

Task 3 – Data transformation

When the Detect Sensitive Data node runs, it converts the id column to string type and it adds a column named DetectedEntities with PII detection metadata to the output. We don’t need to store such metadata information in the target table, and we need to convert the id column back to integer, so let’s add a Change Schema transform node to the ETL job, as shown in the following figure. This will make these changes for us.

Note: You must select the DetectedEntities Drop checkbox for the transform node to drop the added field.

Task 4 – Target data loading

The last task for the ETL job is to establish a connection to the target database and insert the data with PII masked:

  1. Choose AWS Glue Data Catalog from the Targets. This adds a data target node to the canvas.
  2. On the Data target properties panel, choose targetdb-postgresql and target_cx_customer, as shown in the following figure.

Target node added to the ETL Job

Save and run the ETL job

  1. From the Job details tab, for Name, enter ETL - Replicate customer data.
  2. For IAM Role, choose the AWS Glue role created as part of the prerequisites.
  3. Choose Save, then choose Run.

Monitor the job until it successfully finishes from Job run monitoring on the navigation pane.

Step 4 – Verify the results

Connect to the Amazon RDS target database and verify that the replicated rows contain the scrubbed PII data, confirming sensitive information was masked properly in transit between databases as shown in the following figure:Target customer database table with PII data masked.

And that’s it! With AWS Glue Studio, you can create ETL jobs to copy data between databases and transform it along the way without any coding. Try other types of sensitive information for securing your sensitive data during replication. Also try adding and combining multiple and heterogenous data sources and targets.

Clean up

To clean up the resources created:

  1. Delete the AWS Glue ETL job, crawlers, Data Catalog databases, and connections.
  2. Delete the VPC peering connections.
  3. Delete the routes added to the route tables, and inbound rules added to the security groups on the three AWS accounts.
  4. On the AWS Glue account, delete associated Amazon S3 objects. These are in the S3 bucket with aws-glue-assets-account_id-region in its name, where account-id is your AWS Glue account ID, and region is the AWS Region you used.
  5. Delete the Amazon RDS databases you created if you no longer need them. If you used the GitHub repository, then delete the AWS CloudFormation stacks.

Conclusion

In this post, you learned how to use AWS Glue Studio to build an ETL job that copies data from one Amazon RDS database to another and automatically detects PII data and masks the data in-flight, without writing code.

By using AWS Glue for database replication, organizations can eliminate manual processes to find hidden PII and bespoke scripting to transform it by building centralized, visible data sanitization pipelines. This improves security and compliance, and speeds time-to-market for test or analytics data provisioning.


About the Author

Monica Alcalde Angel is a Senior Solutions Architect in the Financial Services, Fintech team at AWS. She works with Blockchain and Crypto AWS customers, helping them accelerate their time to value when using AWS. She lives in New York City, and outside of work, she is passionate about traveling.

Publish packages to AWS CodeArtifact using Amazon CodeCatalyst Actions

Post Syndicated from Muhammad Shahzad original https://aws.amazon.com/blogs/devops/publish-packages-to-aws-codeartifact-using-amazon-codecatalyst-actions/

Amazon CodeCatalyst is a unified software development service for development teams to quickly build, deliver and scale applications on AWS while adhering to organization-specific best practices. Developers can automate development tasks and innovate faster with generative AI capabilities, and spend less time setting up project tools, managing CI/CD pipelines, provisioning and configuring various development environments or coordinating with team members.

It can integrate with services like AWS CodeArtifact, which is a managed artifact repository service that lets you securely store, publish, and share software packages. In this blog post we will show you how to use Publish to AWS CodeArtifact action in a CodeCatalyst workflow to publish packages to AWS Code Artifact.

In Amazon CodeCatalyst, an action is the main building block of a workflow, and defines a logical unit of work to perform during a workflow run. Typically, a workflow includes multiple actions that run sequentially or in parallel depending on how you’ve configured them. Amazon CodeCatalyst provides a library of pre-built actions that you can use in your workflows, such as for building, testing, deploying applications, as well as the ability to create custom actions for specific tasks not covered by the pre-built options.

Following are the instructions on using Publish to AWS CodeArtifact action in Amazon CodeCatalyst workflow.

Prerequisites

To follow along with this walkthrough, you will need:

{
  "Version": "2012-10-17",
  "Statement": [
     {
        "Effect": "Allow",
        "Action": [
           "codeartifact:GetAuthorizationToken",
           "codeartifact:GetRepositoryEndpoint",
           "codeartifact:PublishPackageVersion",
           "codeartifact:PutPackageMetadata",
           "sts:GetServiceBearerToken"
        ],
        "Resource": "*"   
     }
  ]
}

And the following custom trust policy.

{
  "Version": "2012-10-17",
  "Statement": [
     { 
        "Effect": "Allow",
        "Principal": {
          "Service":  [
            "codecatalyst-runner.amazonaws.com",
            "codecatalyst.amazonaws.com"     
           ]  
        },
        "Action": "sts:AssumeRole"   
     }
  ]
}

In the trust policy, we have specified two AWS services in the Principal element. Service principals are defined by the service. The following service principals are defined for CodeCatalyst:

  • amazonaws.com – This service principal is used for a role that will grant CodeCatalyst access to AWS.
  • codecatalyst-runner.amazonaws.com – This service principal is used for a role that will grant CodeCatalyst access to AWS resources in deployments for CodeCatalyst workflows.

Walkthrough

In this example, we are going to publish a npm package to a CodeArtifact repository called ‘myapp-frontend in the domain ‘myapp-artifacts. Amazon CodeCatalyst is available in two regions at the moment i.e. Europe (Ireland) and US West (Oregon). We will use ‘us-west-2’ for all the resources in this walkthrough.

Here are the steps to create your workflow.

  1. In the navigation pane, choose CI/CD, and then choose Workflows.
  2. Choose Create workflow.

The workflow definition file appears in the CodeCatalyst console’s YAML editor.

To configure your workflow 

You can configure your workflow in the Visual editor, or the YAML editor. Let’s start with the YAML editor and then switch to the visual editor.

  1. Choose + Actions to see a list of workflow actions that you can add to your workflow.
  2. In the Build action, choose + to add the action’s YAML to your workflow definition file. Your workflow now looks similar to the following. You can follow the below code by editing in YAML editor.

This image shows the build action from the action drop down list in Amazon CodeCatalyst Workflow.

The following code shows the newly created workflow.

Name: CodeArtifactWorkflow
SchemaVersion: "1.0"

# Optional - Set automatic triggers.
Triggers:
  - Type: Push
    Branches:
      - main

# Required - Define action configurations.
Actions:
  Build:
    # Identifies the action. Do not modify this value.
    Identifier: aws/[email protected]
    # Specifies the source and/or artifacts to pass to the action as input.
    Inputs:
      # Optional
      Sources:
        - WorkflowSource # This specifies that the action requires this Workflow as a source
    Outputs:
      Artifacts:
        - Name: ARTIFACT
          Files:
            - "**/*"
    # Defines the action's properties.
    Configuration:
      # Required - Steps are sequential instructions that run shell commands
      Steps:
        - Run: cd integration/npm/npm-package-example-main
        - Run: npm pack
        - Run: ls
    Compute:
      Type: EC2
    Environment:
      Connections:
        - Role: CodeCatalystWorkflowDevelopmentRole-action-workshop
          Name: codecatalystconnection
      Name: action-builder

In this build action, we are using ‘npm pack’ command to create a compressed tarball (.tgz) file of our package’s source code and configuration files. We are creating an output artifact named ‘ARTIFACT’ and our files are in this directory integration/npm/npm-package-example-master.

Now, we are going to select publish-to-code-artifact action from the action’s dropdown list.

This image shows the Publish to AWS CodeArtifact action from the action drop down list in Amazon CodeCatalyst Workflow.

The following code shows the newly added action in the workflow file.

Publish-to-code-artifact:
    Identifier: .
    
    Environment:
      Connections:
        - Role: CodeCatalystWorkflowDevelopmentRole-action-workshop
          Name: mushhz
      Name: action-builder
      
    Inputs:
      Sources:
        - WorkflowSource
      Artifacts:
        - ARTIFACT
        
    Compute:
      Type: EC2
      
    Configuration:
      PackagePath: /artifacts/Validatepublish-to-code-artifact/ARTIFACT/integration/npm/npm-package-example-main/ktsn-npm-package-example-1.0.1.tgz
      PackageFormat: npm
      RepositoryName: action-builder
      AWSRegion: us-west-2
      DomainName: action-builder

In the above code, you can see we specified the PackageFormat, RepositoryName, DomainName and AWSRegion.These are all required fields.

For Package Path, it is the build artifact output path + the folder path.

You can find the complete workflow file in this GitHub repository.

If you chose ‘Visual’ option to view the workflow definition file in the visual editor. This is going to look as shown in the image below. The fields in the visual editor let you configure the YAML properties shown in the YAML editor.

If you chose ‘Visual’ option to view the workflow definition file in the visual editor. This is going to look as shown in the image below.

How the “Publish to AWS CodeArtifact” action works:

The “Publish to AWS CodeArtifact” action works as follows at runtime:

  • Checks if the PackageFormat, PackagePath, RepositoryName, DomainNameand AWSRegionis specified, validates the configuration, and configures AWS credentials based on the Environment, Connection, and Role specified.
  • Looks for package files to publish in the path configured in the PackagePathfield in the WorkflowSource If no source is configured in Sources, but an artifact is configured in Arifacts, then the action looks for the files in the configured artifact folder.
  • Publishes the package to AWS CodeArtifact.

Cleanup

If you have been following along with this workflow, you should delete the resources you deployed so that you do not continue to incur charges.

  • Delete the published package in AWS CodeArtifact by following these instructions.
  • Delete the repository in AWS CodeArtifact by following these instructions.
  • Delete the domain in AWS CodeArtifact by following these instructions.
  • For Amazon CodeCatalyst, if you created a new project for this tutorial, delete it. For instructions, see Deleting a project. Deleting the project also deletes the source repository and workflow.

Conclusion

In this post, we demonstrated how to use an Amazon CodeCatalyst workflow to publish packages to AWS CodeArtifact by utilizing the Publish to AWS CodeArtifact action. By following the steps outlined in this blog post, you can ensure that your packages are readily available for your projects while maintaining version control and security.

For further reading, see Working with actions in the CodeCatalyst documentation.


About the Authors

Muhammad Shahzad is a Solutions Architect at AWS. He is passionate about helping customers achieve success on their cloud journeys, enjoys designing solutions and helping them implement DevSecOps by explaining principles, creating automated solutions and integrating best practices in their journey to the cloud. Outside of work, Muhammad plays badminton regularly, enjoys various other sports, and has a passion for hiking scenic trails.

Alexander Schueren is a Senior Specialist Solutions Architect at AWS, dedicated to modernizing legacy applications and building event-driven serverless solutions. With a focus on simplifying complexity and bringing clarity to technical challenges, Alexander is on a mission to empower developers with the tools they need for success. As the maintainer of the open-source project “Powertools for AWS Lambda (TypeScript),” he is committed to driving innovation in serverless technologies. In his free time, Alexander channels his creativity through street photography, capturing decisive moments in the urban landscape.
Best Practices for working with Pull Requests in Amazon CodeCatalyst

Post Syndicated from Fahim Sajjad original https://aws.amazon.com/blogs/devops/best-practices-for-working-with-pull-requests-in-amazon-codecatalyst/

According to the Well-Architected DevOps Guidance, “A peer review process for code changes is a strategy for ensuring code quality and shared responsibility. To support separation of duties in a DevOps environment, every change should be reviewed and approved by at least one other person before merging.” Development teams often implement the peer review process in their Software Development Lifecycle (SDLC) by leveraging Pull Requests (PRs). Amazon CodeCatalyst has recently released three new features to facilitate a robust peer review process. Pull Request Approval Rules enforce a minimum number of approvals to ensure multiple peers review a proposed change prior to a progressive deployment. Amazon Q pull request summaries can automatically summarize code changes in a PR, saving time for both the creator and reviewer. Lastly, Nested Comments allows teams to organize conversations and feedback left on a PR to ensure efficient resolution.

This blog will demonstrate how a DevOps lead can leverage new features available in CodeCatalyst to accomplish the following requirements covering best practices: 1. Require at least two people to review every PR prior to deployment, and 2. Reduce the review time to merge (RTTM).

Prerequisites

If you are using CodeCatalyst for the first time, you’ll need the following to follow along with the steps outlined in the blog post:

Pull request approval rules

Approval rules can be configured for branches in a repository. When you create a PR whose destination branch has an approval rule configured for it, the requirements for the rule must be met before the PR can be merged.

In this section, you will implement approval rules on the default branch (main in this case) in the application’s repository to implement the new ask from leadership requiring that at least two people review every PR before deployment.

Step 1: Creating the application
Pull Request approval rules work with every project but in this blog, we’ll leverage the Modern three-tier web application blueprint for simplicity to implement PR approval rules for merging to the main branch.

The image shows the interface of the Amazon CodeCatalyst platform, which allows users to create new projects in three different ways. The three options are "Start with a blueprint", "Bring your own code", and "Start from scratch". In the image, the "Start with a blueprint" option is selected, and the "Modern three-tier web application" blueprint is chosen.

Figure 1: Creating a new Modern three-tier application Blueprint

  1. First, within your space click “Create Project” and select the Modern three-tier web application CodeCatalyst Blueprint as shown above in Figure 1.
  2. Enter a Project name and select: Lambda for the Compute Platform and Amplify Hosting for Frontend Hosting Options. Additionally, ensure your AWS account is selected along with creating a new IAM Role.
  3. Finally, click Create Project and a new project will be created based on the Blueprint.

Once the project is successfully created, the application will deploy via a CodeCatalyst workflow, assuming the AWS account and IAM role were setup correctly. The deployed application will be similar to the Mythical Mysfits website.

Step 2: Creating an approval rule

Next, to satisfy the new requirement of ensuring at least two people review every PR before deployment, you will create the approval rule for members when they create a pull request to merge into the main branch.

  1. Navigate to the project you created in the previous step.
  2. In the navigation pane, choose Code, and then choose Source repositories.
  3. Next, choose the mysfits repository that was created as part of the Blueprint.
    1. On the overview page of the repository, choose Branches.
    2. For the main branch, click View under the Approval Rules column.
  4. In Minimum number of approvals, the number corresponds to the number of approvals required before a pull request can be merged to that branch.
  5. Now, you’ll change the approval rule to satisfy the requirement to ensure at least 2 people review every PR. Choose Manage settings. On the settings page for the source repository, in Approval rules, choose Edit.
  6. In Destination Branch, from the drop-down list, choose main as the name of the branch to configure an approval rule. In Minimum number of approvals, enter 2, and then choose Save.
The image shows an interface for creating an approval rule. It allows users to specify the destination branch and the minimum number of approvals required before a pull request can be merged. In the image, 'main' is selected as the destination branch, and '2' is set as the minimum number of approvals. The interface also provides "Cancel" and "Save" buttons to either discard or commit the approval rule settings.

Figure 2: Creating a new approval rule

Note: You must have the Project administrator role to create and manage approval rules in CodeCatalyst projects. You cannot create approval rules for linked repositories.

When implementing approval rules and branch restrictions in your repositories, ensure you take into consideration the following best practices:

  • For branches deemed critical or important, ensure only highly privileged users are allowed to Push to the Branch and Delete the Branch in the branch rules. This prevents accidental deletion of critical or important branches as well as ensuring any changes introduced to the branch are reviewed before deployment.
  • Ensure Pull Request approval rules are in place for branches your team considers critical or important. While there is no specific recommended number due to varying team size and project complexity, the minimum number of approvals is recommended to be at least one and research has found the optimal number to be two.

In this section, you walked through the steps to create a new approval rule to satisfy the requirement of ensuring at least two people review every PR before deployment on your CodeCatalyst repository.

Amazon Q pull request summaries

Now, you begin exploring ways that can help development teams reduce MTTR. You begin reading about Amazon Q pull request summaries and how this feature can automatically summarize code changes and start to explore this feature in further detail.

While creating a pull request, in Pull request description, you can leverage the Write description for me feature, as seen in Figure 5 below, to have Amazon Q create a description of the changes contained in the pull request.

The image displays an interface for a pull request details page. At the top, it shows the source repository where the changes being reviewed are located, which is "mysfits1ru6c". Below that, there are two dropdown menus - one for the destination branch where the changes will be merged, set to "main", and one for the source branch containing the changes, set to "test-branch". The interface also includes a field for the pull request title, which is set to "Updated Title", and an optional description field. The description field has a button labeled "Write description for me" that allows the user to have the system automatically generate a description for the pull request leveraging Amazon Q.

Figure 3: Amazon Q write description for me feature

Once the description is generated, you can Accept and add to description, as seen in Figure 6 below. As a best practice, once Amazon Q has generated the initial PR summary, you should incorporate any specific organizational or team requirements into the summary before creating the PR. This allows developers to save time and reduce MTTR in generating the PR summary while ensuring all requirements are met.

The image displays an interface for a pull request details page. It shows the source repository as "mystits1ruc" and the destination branch as "main", with the source branch set to "test-branch". The interface also includes a field for the pull request title, which is set to "Updated Title". Underneath that is the optional Pull Request description, which is populated with a description generated from Amazon Q. Below the description field, there are two buttons - "Accept and add to description" and "Hide preview" - that allow the user to accept the description and add it to the pull request.

Figure 4: PR Summary generated by Amazon Q

CodeCatalyst offers an Amazon Q feature that summarizes pull request comments, enabling developers to quickly grasp key points. When many comments are left by reviewers, it can be difficult to understand common themes in the feedback, or even be sure that you’ve addressed all the comments in all revisions. You can use the Create comment summary feature to have Amazon Q analyze the comments and provide a summary for you, as seen in Figure 5 below.

The image shows an interface where pull request title is set to "New Title Update," and the description provides details on the changes being made. Below the description, there is a "Comment summary" section that offers instructions for summarizing the pull request comments. Additionally, there is a "Create comment summary" button, which allows the user to generate a summary of the comments using Amazon Q.

Figure 5: Comment summary

Nested Comments

When reviewing various PRs for the development teams, you notice that feedback and subsequent conversations often happen within disparate and separate comments. This makes reviewing, understanding and addressing the feedback cumbersome and time consuming for the individual developers. Nested Comments in CodeCatalyst can organize conversations and reduce MTTR.

You’ll leverage the existing project to walkthrough how to use the Nested Comments feature:

Step 1: Creating the PR

  1. Click the mysifts repository, and on the overview page of the repository, choose More, and then choose Create branch.
  2. Open the web/index.html file
    • Edit the file to update the text in the <title> block to Mythical Mysfits new title update! and Commit the changes.
  3. Create a pull request by using test-branch as the Source branch and main as the Destination branch. Your PR should now look similar to Figure 6 below:
The image shows the Amazon CodeCatalyst interface, which is used to compare code changes between different revisions of a project. The interface displays a side-by-side view of the "web/index.html" file, highlighting the changes made between the main branch and Revision 1. The differences are ready for review, as indicated by the green message at the top.

Figure 6: Pull Request with updated Title

Step 2: Review PR and add Comments

  1. Review the PR, ensure you are on the Changes tab (similar to Figure 3), click the Comment icon and leave a comment. Normally this would be done by the Reviewer but you will simulate being both the Reviewer and Developer in this walkthrough.
  2. With the comment still open, hit Reply and add another comment as a response to the initial comment. The PR should now look similar to Figure 7 below.
This image shows a pull request interface where changes have been made to the HTML title of a web page. Below the code changes, there is a section for comments related to this pull request. The comments show a nested comments between two developers where they are discussing and confirming the changes to the title.

Figure 7: PR with Nested Comments

When leaving comments on PR in CodeCatalyst, ensure you take into consideration the following best practices :

  • Feedback or conversation focused on a specific topic or piece of code should leverage the nested comments feature. This will ensure the conversation can be easily followed and that context and intent are not lost in a sea of individual comments.
  • Author of the PR should address all comments by either making updates to the code or replying to the comment. This indicates to the reviewer that each comment was reviewed and addressed accordingly.
  • Feedback should be constructive in nature on PRs. Research has found that, “destructive criticism had a negative impact on participants’ moods and motivation to continue working.”

Clean-up

As part of following the steps in this blog post, if you upgraded your space to Standard or Enterprise tier, please ensure you downgrade to the Free tier to avoid any unwanted additional charges. Additionally, delete any projects you may have created during this walkthrough.

Conclusion

In today’s fast-paced software development environment, maintaining a high standard for code changes is crucial. With its recently introduced features, including Pull Request Approval Rules, Amazon Q pull request summaries, and nested comments, CodeCatalyst empowers development teams to ensure a robust pull request review process is in place. These features streamline collaboration, automate documentation tasks, and facilitate organized discussions, enabling developers to focus on delivering high-quality code while maximizing productivity. By leveraging these powerful tools, teams can confidently merge code changes into production, knowing that they have undergone rigorous review and meet the necessary standards for reliability and performance.

About the authors

Brent Everman

Brent is a Senior Technical Account Manager with AWS, based out of Pittsburgh. He has over 17 years of experience working with enterprise and startup customers. He is passionate about improving the software development experience and specializes in AWS’ Next Generation Developer Experience services.

Brendan Jenkins

Brendan Jenkins is a Solutions Architect at Amazon Web Services (AWS) working with Enterprise AWS customers providing them with technical guidance and helping achieve their business goals. He has an area of specialization in DevOps and Machine Learning technology.

Fahim Sajjad

Fahim is a Solutions Architect at Amazon Web Services. He helps customers transform their business by helping in designing their cloud solutions and offering technical guidance. Fahim graduated from the University of Maryland, College Park with a degree in Computer Science. He has deep interested in AI and Machine learning. Fahim enjoys reading about new advancements in technology and hiking.

Abdullah Khan

Abdullah is a Solutions Architect at AWS. He attended the University of Maryland, Baltimore County where he earned a degree in Information Systems. Abdullah currently helps customers design and implement solutions on the AWS Cloud. He has a strong interest in artificial intelligence and machine learning. In his spare time, Abdullah enjoys hiking and listening to podcasts.

Accessing Amazon Q Developer using Microsoft Entra ID and VS Code to accelerate development

Post Syndicated from Mangesh Budkule original https://aws.amazon.com/blogs/devops/accessing-amazon-q-developer-using-microsoft-entra-id-and-vs-code-to-accelerate-development/

Overview

In this blog post, I’ll explain how to use a Microsoft Entra ID and Visual Studio Code editor to access Amazon Q developer service and speed up your development. Additionally, I’ll explain how to minimize the time spent on repetitive tasks and quickly integrate users from external identity sources so they can immediately use and explore Amazon Web Services (AWS).Generative AI on AWS holds great ability for businesses seeking to unlock new opportunities and drive innovation. AWS offers a robust suite of tools and capabilities that can revolutionize software development, generate valuable insights, and deliver enhanced customer value. AWS is committed to simplifying generative AI for businesses through services like Amazon Q, Amazon Bedrock, Amazon SageMaker, Data foundation & AI infrastructure.

Amazon Q Developer is a generative AI-powered assistant that helps developers and IT professionals with all of their tasks across the software development lifecycle. Amazon Q Developer assists with coding, testing, and upgrading to troubleshooting, performing security scanning and fixes, optimizing AWS resources, and creating data engineering pipelines.

A common request from Amazon Q Developer customers is to allow developer sign-ins using established identity providers (IdP) such as Entra ID. Amazon Q Developer offers authentication support through AWS Builder ID or AWS IAM Identity Center. AWS Builder ID is a personal profile for builders. IAM Identity Center is ideal for an enterprise developer working with Amazon Q and employed by organizations with an AWS account. When using the Amazon Q Developer Pro tier, the developer should authenticate with the IAM Identity Center. See the documentation, Understanding tiers of service for Amazon Q Developer for more information.

How it works

The flow for accessing Amazon Q Developer through the IAM Identity Center involves the authentication of Entra ID users using Security Assertion Markup Language (SAML) 2.0 authentication (Figure 1).

The diagram explains you the flow for accessing Amazon Q Developer through the IAM Identity Center involves the authentication of Entra ID users using SAML 2.0 authentication.

Figure 1 – Solution Overview

The flow for accessing Amazon Q Developer through the IAM Identity Center involves the authentication of Entra ID users using SAML 2.0 authentication. (Figure 1).

  1. IAM Identity Center synchronizes users and groups information from Entra ID into IAM Identity Center using the System for Cross-domain Identity Management (SCIM) v2.0 protocol.
  2. Developers with an Entra ID account connect to Amazon Q Developer through IAM Identity Center using the VS Code IDE.
  3. If a developer isn’t already authenticated, they will be redirected to the Entra ID account login. The developer will sign in using their Entra ID credentials.
  4. If the sign-in is successful, Entra ID processes the request and sends a SAML response containing the developer identity and authentication status to IAM Identity Center.
  5. If the SAML response is valid and the developer is authenticated, IAM Identity Center grants access to Amazon Q Developer.
  6. The developer can now securely access and use Amazon Q Developer.

Prerequisites

In order to perform the following procedure, make sure the following are in place.

Walkthrough

Configure Entra ID and AWS IAM Identity Center integration

In this section, I will show how you can create a SAML base connection between Entra ID and AWS Identity Center so you can access AWS generative AI services using your Entra ID.

Note: You need to switch the console between Entra ID portal and AWS IAM Identity center. I recommend to open new browser tabs for each console.

Step 1 – Prepare your Microsoft tenant

Perform the below steps in the Entra identity provider section.

Entra ID configuration.

  1. Sign in to the Microsoft Entra admin center with a minimum permission set of a Cloud Application Administrator.
  2. Navigate to Identity > Applications > Enterprise applications, and then choose New application.
  3. On the Browse Microsoft Entra Gallery page, enter AWS IAM Identity Center in the search box.
  4. Select AWS IAM Identity Center from the results area.
  5. Choose Create.

Now you have created AWS IAM Identity Center application, set up single sign-on to enable users to sign into their applications using their Entra ID credentials. Select the Single sign-on tab from the left navigation plane and select Setup single sign on.

Step 2 – Collect required service provider metadata from IAM Identity Center

In this step, you will launch the Change identity source wizard from within the IAM Identity Center console and retrieve the metadata file and the AWS specific sign-in URL. You will need this to enter when configuring the connection with Entra ID in the next step.

IAM Identity Center.

You need to enable this in order to configure SSO.

  1. Navigate to Services –> Security, Identity, & Compliance –> AWS IAM Identity Center.
  2. Choose Enable (Figure 2).

    This diagram illustrates , how you can enable AWS IAM Identity Center

    Figure 2 – Get started with AWS IAM Identity Center

  3. In the left navigation pane, choose Settings.
  4. On the Settings page, find Identity source, select Actions pull-down menu, and select Change identity source.
  5. On the Change identity source page, choose External identity provider (Figure 3).
    This diagram illustrates how to choose an External identity provider in the Source account when using AWS Identity Center.

    Figure 3 – Select External identity provider

  6. On the Configure external identity provider page, under Service provider metadata, select Download metadata file (XML file).
  7. In the same section, locate the AWS access portal sign-in URL value and copy it. You will need to enter this value when prompted in the next step (Figure 4).

    The diagram illustrates the sources for downloading and copying the metadata URLs of service providers.

    Figure 4 – Copy provider metadata URLs

Leave this page open, and move to the next step to configure the AWS IAM Identity Center enterprise application in Entra ID. Later, you will return to this page to complete the process.

Step 3 – Configure the AWS IAM Identity Center enterprise application in Entra ID

This procedure establishes one-half of the SAML connection on the Microsoft side using the values from the metadata file and Sign-On URL you obtained in the previous step.

  1. In the Microsoft Entra admin center console, navigate to Identity > Applications > Enterprise applications and then choose AWS IAM Identity Center.
  2. On the left, choose Single sign-on.
  3. On the Set up Single sign on with SAML page, choose Upload metadata file, choose the folder icon, select the service provider metadata file that you downloaded in the previous step 2.6, and then choose Add.
  4. On the Basic SAML Configuration page, verify that both the Identifier and Reply URL values now point to endpoints in AWS that start with https://<REGION>.signin.aws.amazon.com/platform/saml/.
  5. Under Sign on URL (Optional), paste in the AWS access portal sign-in URL value you copied in the previous step (Step 2.7), choose Save, and then choose X to close the window.
  6. If prompted to test single sign-on with AWS IAM Identity Center, choose No I’ll test later. You will do this verification in a later step.
  7. On the Set up Single Sign-On with SAML page, in the SAML Certificates section, next to Federation Metadata XML, choose Download to save the metadata file to your system. You will need to upload this file when prompted in the next step.

Step 4 – Configure the Entra ID external IdP in AWS IAM Identity Center

Next you will return to the Change identity source wizard in the IAM Identity Center console to complete the second-half of the SAML connection in AWS.

  1. Return to the browser session you left open in the IAM Identity Center console.
  2. On the Configure external identity provider page, in the Identity provider metadata section, under IdP SAML metadata, choose the Choose file button, and select the identity provider metadata file that you downloaded from Microsoft Entra ID in the previous step, and then choose Open (Figure 5).

    This diagram illustrate AWS IAM Identity center metadata

    Figure 5 – AWS IAM Identity center metadata

  3. Choose Next
  4. After you read the disclaimer and are ready to proceed, enter ACCEPT
  5. Choose Change identity source to apply your changes (Figure 6).

    The diagram illustrates AWS IAM Identity center metadata change request acceptance.

    Figure 6 – AWS IAM Identity center metadata

  6. Confirm the changes (Figure 7).

    The diagram illustrates AWS IAM Identity center metadata configuration changes progress information.

    Figure 7 – AWS IAM Identity center metadata configuration changes progress console.

Step 5 – Configure and test your SCIM synchronization

In this step, you will set up automatic provisioning (synchronization) of user and group information from Microsoft Entra ID into IAM Identity Center using the SCIM v2.0 protocol. You configure this connection in Microsoft Entra ID using your SCIM endpoint for AWS IAM Identity Center and a bearer token that is created automatically by AWS IAM Identity Center.

To enable automatic provisioning of Entra ID users to IAM Identity Center, follow these steps using the IAM Identity Center application in Entra ID. For testing purposes, you can create a new user (TestUser) in Entra ID with details like First Name, Last Name, Email ID, Department, and more. Once you’ve configured SCIM synchronization, you can verify that this user and their relevant attributes were successfully synced to AWS IAM Identity Center.

In this procedure, you will use the IAM Identity Center console to enable automatic provisioning of users and groups coming from Entra ID into IAM Identity Center.

  1. Open the IAM Identity Center console and Choose Setting in the left navigation pane.
  2. On the Settings page, under the Identity source tab, notice that Provisioning method is set to Manual (Figure 8).

    This diagram illustrates provisioning method configuration details

    Figure 8 – AWS IAM Identity center console with provisioning method configuration details

  3. Locate the Automatic provisioning information box, and then choose Enable. This immediately enables automatic provisioning in IAM Identity Center and displays the necessary SCIM endpoint and access token information.
  4. In the Inbound automatic provisioning dialog box, copy each of the values for the following options. You will need to paste these in the next step when you configure provisioning in Entra ID.
  5. SCIM endpoint – For example, https://scim.us-east-2.amazonaws.com/11111111111-2222-3333-4444-555555555555/scim/v2/
  6. Access token – Choose Show token to copy the value (Figure 9).
    The diagram illustrates SCIM endpoint URL and Access token information.

    Figure 9 – AWS IAM Identity center automatic provisioning info

  7. Choose Close.
  8. Under the Identity source tab, notice that Provisioning method is now set to SCIM.

Step 6 – Configure automatic provisioning in Entra ID

Now that you have your test user in place and have enabled SCIM in IAM Identity Center, you can proceed with configuring the SCIM synchronization settings in Entra ID.

  1. In the Microsoft Entra admin center console, navigate to Identity > Applications > Enterprise applications and then choose AWS IAM Identity Center.
  2. Choose Provisioning, under Manage, choose Provisioning
  3. In Provisioning Mode select
  4. For Admin Credentials, in Tenant URL paste in the SCIM endpoint URL value you copied earlier. In Secret Token, paste in the Access token value (Figure 10).

    The diagram illustrates Azure Enterprise AWS IAM Identity center application provisioning configuration tab

    Figure 10 – Azure Enterprise AWS IAM Identity center application provisioning configuration tab

  5. Choose Test Connection. You should see a message indicating that the tested credentials were successfully authorized to enable provisioning (Figure 11).

    This diagram illustrates AWS IAM Identity center application provisioning testing status

    Figure 11 – Azure Enterprise AWS IAM Identity center application provisioning testing status

  6. Choose Save.
  7. Under Manage, choose Users and groups, and then choose Add user/group.
  8. On the Add Assignment page, under Users, choose None Selected.
  9. Select TestUser, and then choose Select.
  10. On the Add Assignment page, choose
  11. Choose Overview, and then choose Start provisioning (Figure 12).
    The diagram shows the process of manually initiating provisioning through the Azure AWS IAM Identity center application.

    Figure 12 – AWS IAM Identity center application Start provisioning tab

    Note : The default provisioning interval is set to 40 minutes. Our users (Figure 13) are successfully provisioned and are now available in the AWS IAM Identity Center console.

In this section, you will verify that TestUser user was successfully provisioned and that all attributes are displayed in IAM Identity Center (Figure 13).

This diagram shows the user console of AWS IAM Identity center application.

Figure 13 – AWS IAM Identity center application user console example

Preview (opens in a new tab)

In the Identity source in IDC section, enable Identity-aware console sessions (Figure 14). This enables AWS IAM Identity Center user and session IDs to be included in users’ AWS console sessions when they sign in. For example, Amazon Q Developer Pro uses identity-aware console sessions to personalize the service experience.

The diagram illustrates how you can enable Identity aware console sessions

Figure 14 – Enable Identity aware console sessions

I have completed Entra ID and AWS Identity Center configuration. You can see Entra ID identity synced successfully with AWS IAM identity center.

Step 7 – Set up AWS Toolkit with IAM Identity Center

To use Amazon Q Developer, you will now set up the AWS Toolkit within integrated development environments (IDE) to establish authentication with the IAM Identity Center.

AWS Toolkit for Visual Studio Code is an open-source plug-in for VS Code that makes it easier for developers by providing an integrated experience to create, debug, and deploy applications on AWS. Getting started with Amazon Q Developer in VS Code is simple.

  1. Open the AWS Toolkit for Visual Studio Code extension in your VS Code IDE. Install AWS Toolkit for VS Code, which is available as a download from the VS Code Marketplace.
  2. From the AWS Toolkit for Visual Studio Code extension in the VS Code Marketplace, choose Install to begin the installation process.
  3. When prompted, choose to restart VS Code to complete the installation process.

Step 8 – Setup Amazon Q Developer service with VS Code using AWS IAM identity center.

After installing the Amazon Q extension or plugin, authenticate through IAM Identity Center or AWS Builder ID.

After your identity has been subscribed to Amazon Q Developer Pro, complete the following steps to authenticate.

  1. Install the Amazon Q IDE extension or plugin in your Visual Studio Code.
  2. Choose the Amazon Q icon from the sidebar in your IDE
  3. Choose Use with Pro license and select Continue (Figure 15).

    The diagram illustrates how you can use Visual Studio code IDE with Amazon Q Developer extension.

    Figure 15 – Visual Studio code Amazon Q Developer extension

  4. Enter the IAM Identity Center URL you previously copied into the Start URL
  5. Set the appropriate region, example us-east-1, and select Continue
  6. Click Copy Code and Proceed to copy the code from the resulting pop-up.
  7. When prompted by the Do you want Code to open the external website? pop-up, select Open
  8. Paste the code copied in Step 6 and select Next
  9. Enter your Entra ID credentials and select Sign in
  10. Select Allow Access to AWS IDE Extensions for VSCode to access Amazon Q Developer (Figure 16).

    The diagram illustrates how can you provide VS code IDE permission to access Amazon Q service.

    Figure 16 – Allow VS Code to access Amazon Q Developer

  11. When the connection is complete, a notification indicates that it is safe to close your browser. Close the browser tab and return to your IDE.
  12. You are now all set to use Amazon Q Developer from within IDE, authenticated with your Entra ID credentials.

Step 9 – Test configuration examples

Now you have configured IAM identity Center access with VS code now you can chat, get inline code suggestions, check for security vulnerabilities with Amazon Q Developer to learn about, build, and operate AWS applications. I have mentioned a few examples of Amazon Q Suggestions, Code suggestions, Security Vulnerabilities during development for your reference (Figures 17 ,18 ,19 ,20).

The diagram illustrates how to seek assistance from Amazon Q.

Figure 17 – Amazon Q suggestion examples

Example of developers get the recommendations using Amazon Q developer.

This diagram shows an example of Amazon Q Developer.

Figure 18 – Amazon Q Developer example

This diagram show the example of software development using AWS Amazon Q

Figure 19 – Generate code, explain code, and get answers to questions about software development.

Example of integrating secure coding practices early in the software development lifecycle using Amazon Q developer.

This diagram shows the example of how to Analyze and fix security vulnerabilities in your project example using Amazon Q

Figure 20 – Analyze and fix security vulnerabilities in your project example

Cleanup

Configuring AWS and Azure services from this blog will provision resources which incur cost. It is a best practice to delete configurations and resources that you are no longer using so that you do not incur unintended charges.

 Conclusion

In this blog post, you learned how to integrate AWS IAM Identity Center and Entra ID IdP for accessing Amazon Q Developer service using VS Code IDE, which speeds up development. Next, you set up the AWS Toolkit to establish a secure connection to AWS using Entra ID credentials, granting you access to the Amazon Q Developer Professional Tier. Using SCIM automatic provisioning for user provisioning and access assignment saves time and speeds up onboarding, allowing for immediate use of AWS services using you own identity. Using Amazon Q, developers get the recommendations and information within their working environment in the IDE, enabling them to integrate secure coding practices early in the software development lifecycle. Developers can proactively scan their existing code using Amazon Q and remediate the security vulnerabilities found in the code.

To learn more about the AWS services

AWS Toolkit for Visual Studio Code

What is IAM Identity Center?

Configure SAML and SCIM with Microsoft Entra ID and IAM Identity Center

How to use Amazon CodeWhisperer using Okta as an external IdP

Mangesh Budkule

Mangesh Budkule is a Sr. Microsoft Specialist Solution architect at AWS with 20 years of experience in the technology industry. Using his passion to bridge the gap between technology and business, he works with our customers to provide architectural guidance and technical assistance on AWS Services, improving the value of their solutions to achieve their business outcomes.