Tag Archives: Uncategorized

Как да разпознаем е-майл скам

Post Syndicated from original http://www.gatchev.info/blog/?p=2586

From: Български пощи – [email protected]

To: grigor@(моят сайт)

Subject: Имате транзитна пратка BG51300A76

Имате пакет в транзит


Уважаеми клиенти,
 
Получихте пакет BG51300A76 на домашния си адрес от подателя: Apple Inc
 
За да гарантирате доставката на вашия пакет навреме, трябва да потвърдите своята самоличност и адрес за фактуриране.
 

Моля, изпратете ни предната и задната страна на вашата (лична карта, шофьорска книжка) на имейл адрес: [email protected]


Важна забележка: Ако не платите в рамките на времеви прозорец от 24 часа, ще бъдем принудени да върнем пакета на подателя.

Какво ще кажете за това писмо? Истинско ли е, или е измама? Какво ще изпуснете, ако не си изпратите документите на посочения е-майл?

Ако не можете да решите, информацията надолу може да ви е полезна.


Като начало, кой го праща?

Адресът на изпращача е просто текстово поле – всеки може да напише каквото си иска в него, точно както всеки може да напише каквото си иска на редовете за изпращач на плик за писма. Той не значи абсолютно нищо.

(Освен ако, разбира се, скамерът не е изключително завеян. А в този случай очевидно е. Подаденият е-майл адрес – не написаното име „Български пощи“ – е [email protected]. Здрасти Гугъл, абе това ли е сайтът на Български пощи? Я, не бил този – бил bgpost.bg. Че защо Български пощи ще ви пишат от сайт, различен от техния?)

После, на кой е-майл адрес се очаква да пратите потвърждение? [email protected]? Изглежда убедително, но… всеки може да си регистрира домейн с такова име. Защо ще им е на Български пощи да получават верификации на сайт, различен от техния?

И ако това са червени флагове, следващото е червена свръхнова. Не се ли очаква документите ви да ги провери служителят, който ти дава пратката?Откога пощите почнаха да ги искат по мейла? Съвсем лесно е да изфотошопите нещо, което може да мине за снимка на лични документи – пощите толкова ли са глупави, че да не го знаят?…

Е, добре. Да кажем, че в момента наистина очаквате пратка от Apple и се колебаете дали не е тази. Нека проверим нещата малко по-надълбоко.

Като начало, каква е истинската информация в този е-майл? Я да погледнем!

В повечето е-майл клиенти има възможност да видите за мейла „headers“, „подробна информация“ или който програмист както му е хрумнало да го кръсти. Ако пробвате, ще го намерите. Като го отворите, изглежда горе-долу така:

Return-Path: <[email protected]>
Delivered-To: grigor@(моят сайт)
Received: from localhost (localhost [127.0.0.1])
     by mail.serdica.org (Postfix) with ESMTP id AF5F12208CB076
     for <grigor@(моят сайт)>; Fri, 2 Jun 2023 22:34:51 +0300 (EEST)
Authentication-Results: mail.serdica.org; dkim=fail
     reason=”verification failed; insecure key”
     header.d=sitepointhosting.com [email protected]
     header.b=WW6zegzd; dkim-adsp=none (insecure policy);
     dkim-atps=neutral
Received: from mail.serdica.org ([127.0.0.1])
     by localhost (mail1.serdica.org [127.0.0.1]) (amavisd-new, port 10024)
     with ESMTP id sncAcSTFhyIE for <grigor@(моят сайт)>;
     Fri, 2 Jun 2023 22:34:50 +0300 (EEST)
Received: from li1510-106.members.linode.com (li1510-106.members.linode.com [139.162.225.106])
     by mail.serdica.org (Postfix) with ESMTPS id 063742208CB06E
     for <grigor@(моят сайт)>; Fri, 2 Jun 2023 22:34:49 +0300 (EEST)
DKIM-Signature: v=1; a=rsa-sha256; q=dns/txt; c=relaxed/relaxed;
     d=sitepointhosting.com; s=default; h=Content-Transfer-Encoding:Content-Type:
     Subject:Date:To:From:MIME-Version:Sender:Reply-To:Message-ID:Cc:Content-ID:
     Content-Description:Resent-Date:Resent-From:Resent-Sender:Resent-To:Resent-Cc
     :Resent-Message-ID:In-Reply-To:References:List-Id:List-Help:List-Unsubscribe:
     List-Subscribe:List-Post:List-Owner:List-Archive;
     bh=mMbL5+xGo2Iedd/PhkEUEveb2E6pTaGkQTviXgmR+7I=; b=WW6zegzdR5Vr2Vt4+4umsQg8mk
     +aPz0lN5kWGz3bDbNEhPEBeNixacvshGQHG9epvlXY4K/ArQAoMrDidYbBjAzjFqvTF1Yyx8PxVD+
     p2RRc4pvt6G6UTTjBQq71sBQ6CWVuE4BC7bgo20fIzASbLWBJoXjo2TWqPOyoAOJuHJApUZYB56GO
     stQQ3kSHcOmQI0kun8XZjHCnlep9WfdRYzkeG0QHh9Z4k7KjE2XrFaHLUnaa9q77w2bP4zOh/hfme
     4/qBRw206KH6Xtaxav2ko8a5gj/wBe9MbswS6x/kheDEi+cpHdGBRtPLGwdyB51X3BRQUosSu30Je
     PaxiS9GA==;
Received: from [217.61.23.188] (port=62629 helo=GRANDCUSTOMWO)
     by administration.sitepointhosting.com with esmtpsa (TLS1.2) tls TLS_ECDHE_RSA_WITH_AES_256_GCM_SHA384
     (Exim 4.96)
     (envelope-from <[email protected]>)
     id 1q5AXu-0001r5-2p
     for grigor@(моят сайт);
     Fri, 02 Jun 2023 19:34:46 +0000
MIME-Version: 1.0
From: =?utf-8?Q?=D0=91=D1=8A=D0=BB=D0=B3=D0=B0=D1=80=D1=81=D0=BA=D0=B8?=
     =?utf-8?Q?_=D0=BF=D0=BE=D1=89=D0=B8?= <[email protected]>
To: grigor@(моят сайт)
Date: 2 Jun 2023 21:34:49 +0200
Subject: =?utf-8?B?0JjQvNCw0YLQtSDRgtGA0LDQvdC30LjRgtC90LAg0L/RgNCw?=
     =?utf-8?B?0YLQutCwIEJHNTEzMDBBNzY=?=
Content-Type: text/html; charset=utf-8
Content-Transfer-Encoding: base64

Оказва се, че изпращачът на мейла го релейва през сървър на домейн, който даже си няма сайт – sitepointhosting.com. Реалните Български пощи дали си хостват нещата при външен провайдер, и то такъв, дето дори сайт не се е погрижил да си направи?

Те пък, ако съдя по записа, са получили този мейл от IP адрес 217.61.23.188. Къде се намира този IP адрес? Я да питаме iplocation.net… Великобритания? Колко интересно. Български пощи се намират във Великобритания?

А къде се намира този фамозен домейн bg-post-tracking.com?

Пишем в конзолка: ping bg-post-tracking.com

Отоворът е: 64 bytes from 149.100.155.250 (149.100.155.250): (разни подробности)

Значи IP адресът на сайта е 149.100.155.250. Здрасти пак iplocation.net, къде се намира пък този IP адрес? Я – Бразилия. Откъде Български пощи били следели пратките си…


Има ли още някой, който да не е наясно какво ще получи, ако прати документите си по посочения начин? Бих го разбрал – вариантите не са малко. Милиони дългове на негово име, нотариален акт за прехвърляне на апартамента му на някоя мутра, присъда за трафик на наркотици или убийства, дадена на някой с тези документи… реалността е богата.

Благодаря за вниманието.

Open-Source LLMs

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/06/open-source-llms.html

In February, Meta released its large language model: LLaMA. Unlike OpenAI and its ChatGPT, Meta didn’t just give the world a chat window to play with. Instead, it released the code into the open-source community, and shortly thereafter the model itself was leaked. Researchers and programmers immediately started modifying it, improving it, and getting it to do things no one else anticipated. And their results have been immediate, innovative, and an indication of how the future of this technology is going to play out. Training speeds have hugely increased, and the size of the models themselves has shrunk to the point that you can create and run them on a laptop. The world of AI research has dramatically changed.

This development hasn’t made the same splash as other corporate announcements, but its effects will be much greater. It will wrest power from the large tech corporations, resulting in both much more innovation and a much more challenging regulatory landscape. The large corporations that had controlled these models warn that this free-for-all will lead to potentially dangerous developments, and problematic uses of the open technology have already been documented. But those who are working on the open models counter that a more democratic research environment is better than having this powerful technology controlled by a small number of corporations.

The power shift comes from simplification. The LLMs built by OpenAI and Google rely on massive data sets, measured in the tens of billions of bytes, computed on by tens of thousands of powerful specialized processors producing models with billions of parameters. The received wisdom is that bigger data, bigger processing, and larger parameter sets were all needed to make a better model. Producing such a model requires the resources of a corporation with the money and computing power of a Google or Microsoft or Meta.

But building on public models like Meta’s LLaMa, the open-source community has innovated in ways that allow results nearly as good as the huge models—but run on home machines with common data sets. What was once the reserve of the resource-rich has become a playground for anyone with curiosity, coding skills, and a good laptop. Bigger may be better, but the open-source community is showing that smaller is often good enough. This opens the door to more efficient, accessible, and resource-friendly LLMs.

More importantly, these smaller and faster LLMs are much more accessible and easier to experiment with. Rather than needing tens of thousands of machines and millions of dollars to train a new model, an existing model can now be customized on a mid-priced laptop in a few hours. This fosters rapid innovation.

It also takes control away from large companies like Google and OpenAI. By providing access to the underlying code and encouraging collaboration, open-source initiatives empower a diverse range of developers, researchers, and organizations to shape the technology. This diversification of control helps prevent undue influence, and ensures that the development and deployment of AI technologies align with a broader set of values and priorities. Much of the modern internet was built on open-source technologies from the LAMP (Linux, Apache, mySQL, and PHP/PERL/Python) stack—a suite of applications often used in web development. This enabled sophisticated websites to be easily constructed, all with open-source tools that were built by enthusiasts, not companies looking for profit. Facebook itself was originally built using open-source PHP.

But being open-source also means that there is no one to hold responsible for misuse of the technology. When vulnerabilities are discovered in obscure bits of open-source technology critical to the functioning of the internet, often there is no entity responsible for fixing the bug. Open-source communities span countries and cultures, making it difficult to ensure that any country’s laws will be respected by the community. And having the technology open-sourced means that those who wish to use it for unintended, illegal, or nefarious purposes have the same access to the technology as anyone else.

This, in turn, has significant implications for those who are looking to regulate this new and powerful technology. Now that the open-source community is remixing LLMs, it’s no longer possible to regulate the technology by dictating what research and development can be done; there are simply too many researchers doing too many different things in too many different countries. The only governance mechanism available to governments now is to regulate usage (and only for those who pay attention to the law), or to offer incentives to those (including startups, individuals, and small companies) who are now the drivers of innovation in the arena. Incentives for these communities could take the form of rewards for the production of particular uses of the technology, or hackathons to develop particularly useful applications. Sticks are hard to use—instead, we need appealing carrots.

It is important to remember that the open-source community is not always motivated by profit. The members of this community are often driven by curiosity, the desire to experiment, or the simple joys of building. While there are companies that profit from supporting software produced by open-source projects like Linux, Python, or the Apache web server, those communities are not profit driven.

And there are many open-source models to choose from. Alpaca, Cerebras-GPT, Dolly, HuggingChat, and StableLM have all been released in the past few months. Most of them are built on top of LLaMA, but some have other pedigrees. More are on their way.

The large tech monopolies that have been developing and fielding LLMs—Google, Microsoft, and Meta—are not ready for this. A few weeks ago, a Google employee leaked a memo in which an engineer tried to explain to his superiors what an open-source LLM means for their own proprietary tech. The memo concluded that the open-source community has lapped the major corporations and has an overwhelming lead on them.

This isn’t the first time companies have ignored the power of the open-source community. Sun never understood Linux. Netscape never understood the Apache web server. Open source isn’t very good at original innovations, but once an innovation is seen and picked up, the community can be a pretty overwhelming thing. The large companies may respond by trying to retrench and pulling their models back from the open-source community.

But it’s too late. We have entered an era of LLM democratization. By showing that smaller models can be highly effective, enabling easy experimentation, diversifying control, and providing incentives that are not profit motivated, open-source initiatives are moving us into a more dynamic and inclusive AI landscape. This doesn’t mean that some of these models won’t be biased, or wrong, or used to generate disinformation or abuse. But it does mean that controlling this technology is going to take an entirely different approach than regulating the large players.

This essay was written with Jim Waldo, and previously appeared on Slate.com.

EDITED TO ADD (6/4): Slashdot thread.

Version 1 of the AWS Cloud Development Kit (AWS CDK) has reached end-of-support

Post Syndicated from Evgeny Karasik original https://aws.amazon.com/blogs/devops/cdk-v1-end-of-support/

Since its introduction in 2018, AWS CDK has gained significant traction among developers for building Infrastructure as Code solutions. As technology advances and new features emerge, it is inevitable that older versions of tools must reach their end-of-support.

As of June 1, 2023, AWS CDK v1 has officially reached its end-of-support. Consequently, AWS will no longer provide maintenance, updates, patches, or technical support for this version of the CDK. While the existing releases will remain accessible through public package managers and the code will still be available on GitHub, using the older AWS CDK v1 could expose your code to security vulnerabilities and unaddressed bugs. Moreover, as the technology landscape evolves, new AWS services and features may not be compatible with the outdated version. This could result in compatibility issues, lack of support for newer services, and missed opportunities to leverage the latest innovations from AWS.

To mitigate the risks associated with using an unsupported AWS CDK version and to benefit from the inclusion of new features and capabilities, we strongly recommends that you transition to AWS CDK v2 without delay.

AWS CDK version 2 (v2) provides improved features, enhanced performance, and continued support from AWS. By embracing the latest version of AWS CDK, developers can ensure the security, compatibility, and stability of their infrastructure as code solutions on AWS. Moving to AWS CDK v2 is typically a straightforward process for most projects. It involves a one-time, secure re-bootstrapping of your AWS accounts, along with updating dependencies and making changes to import statements.

To learn more, refer to the following resources:

  • To identify stacks deployed with AWS CDK v1, use the awscdk-v1-stack-finder utility.
  • To compare AWS CDK v1 and v2, consult the “Migrating to AWS CDK v2” section in the AWS CDK Developer Guide. It provides the necessary information for a smooth transition between the two versions.
  • Connect with the community in the cdk.dev Slack workspace.
  • Open a discussion or issue on GitHub if you have questions when migrating, or run into issues.

On the Catastrophic Risk of AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/06/on-the-catastrophic-risk-of-ai.html

Earlier this week, I signed on to a short group statement, coordinated by the Center for AI Safety:

Mitigating the risk of extinction from AI should be a global priority alongside other societal-scale risks such as pandemics and nuclear war.

The press coverage has been extensive, and surprising to me. The New York Times headline is “A.I. Poses ‘Risk of Extinction,’ Industry Leaders Warn.” BBC: “Artificial intelligence could lead to extinction, experts warn.” Other headlines are similar.

I actually don’t think that AI poses a risk to human extinction. I think it poses a similar risk to pandemics and nuclear war—which is to say, a risk worth taking seriously, but not something to panic over. Which is what I thought the statement said.

In my talk at the RSA Conference last month, I talked about the power level of our species becoming too great for our systems of governance. Talking about those systems, I said:

Now, add into this mix the risks that arise from new and dangerous technologies such as the internet or AI or synthetic biology. Or molecular nanotechnology, or nuclear weapons. Here, misaligned incentives and hacking can have catastrophic consequences for society.

That was what I was thinking about when I agreed to sign on to the statement: “Pandemics, nuclear weapons, AI—yeah, I would put those three in the same bucket. Surely we can spend the same effort on AI risk as we do on future pandemics. That’s a really low bar.” Clearly I should have focused on the word “extinction,” and not the relative comparisons.

Seth Lazar, Jeremy Howard, and Arvind Narayanan wrote:

We think that, in fact, most signatories to the statement believe that runaway AI is a way off yet, and that it will take a significant scientific advance to get there­—ne that we cannot anticipate, even if we are confident that it will someday occur. If this is so, then at least two things follow.

I agree with that, and with their follow up:

First, we should give more weight to serious risks from AI that are more urgent. Even if existing AI systems and their plausible extensions won’t wipe us out, they are already causing much more concentrated harm, they are sure to exacerbate inequality and, in the hands of power-hungry governments and unscrupulous corporations, will undermine individual and collective freedom.

This is what I wrote in Click Here to Kill Everybody (2018):

I am less worried about AI; I regard fear of AI more as a mirror of our own society than as a harbinger of the future. AI and intelligent robotics are the culmination of several precursor technologies, like machine learning algorithms, automation, and autonomy. The security risks from those precursor technologies are already with us, and they’re increasing as the technologies become more powerful and more prevalent. So, while I am worried about intelligent and even driverless cars, most of the risks arealready prevalent in Internet-connected drivered cars. And while I am worried about robot soldiers, most of the risks are already prevalent in autonomous weapons systems.

Also, as roboticist Rodney Brooks pointed out, “Long before we see such machines arising there will be the somewhat less intelligent and belligerent machines. Before that there will be the really grumpy machines. Before that the quite annoying machines. And before them the arrogant unpleasant machines.” I think we’ll see any new security risks coming long before they get here.

I do think we should worry about catastrophic AI and robotics risk. It’s the fact that they affect the world in a direct, physical manner—and that they’re vulnerable to class breaks.

(Other things to read: David Chapman is good on scary AI. And Kieran Healy is good on the statement.)

Okay, enough. I should also learn not to sign on to group statements.

Chinese Hacking of US Critical Infrastructure

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/05/chinese-hacking-of-us-critical-infrastructure.html

Everyone is writing about an interagency and international report on Chinese hacking of US critical infrastructure.

Lots of interesting details about how the group, called Volt Typhoon, accesses target networks and evades detection.

Brute-Forcing a Fingerprint Reader

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/05/brute-forcing-a-fingerprint-reader.html

It’s neither hard nor expensive:

Unlike password authentication, which requires a direct match between what is inputted and what’s stored in a database, fingerprint authentication determines a match using a reference threshold. As a result, a successful fingerprint brute-force attack requires only that an inputted image provides an acceptable approximation of an image in the fingerprint database. BrutePrint manipulates the false acceptance rate (FAR) to increase the threshold so fewer approximate images are accepted.

BrutePrint acts as an adversary in the middle between the fingerprint sensor and the trusted execution environment and exploits vulnerabilities that allow for unlimited guesses.

In a BrutePrint attack, the adversary removes the back cover of the device and attaches the $15 circuit board that has the fingerprint database loaded in the flash storage. The adversary then must convert the database into a fingerprint dictionary that’s formatted to work with the specific sensor used by the targeted phone. The process uses a neural-style transfer when converting the database into the usable dictionary. This process increases the chances of a match.

With the fingerprint dictionary in place, the adversary device is now in a position to input each entry into the targeted phone. Normally, a protection known as attempt limiting effectively locks a phone after a set number of failed login attempts are reached. BrutePrint can fully bypass this limit in the eight tested Android models, meaning the adversary device can try an infinite number of guesses. (On the two iPhones, the attack can expand the number of guesses to 15, three times higher than the five permitted.)

The bypasses result from exploiting what the researchers said are two zero-day vulnerabilities in the smartphone fingerprint authentication framework of virtually all smartphones. The vulnerabilities—­one known as CAMF (cancel-after-match fail) and the other MAL (match-after-lock)—result from logic bugs in the authentication framework. CAMF exploits invalidate the checksum of transmitted fingerprint data, and MAL exploits infer matching results through side-channel attacks.

Depending on the model, the attack takes between 40 minutes and 14 hours.

Also:

The ability of BrutePrint to successfully hijack fingerprints stored on Android devices but not iPhones is the result of one simple design difference: iOS encrypts the data, and Android does not.

Other news articles. Research paper.

Expeditionary Cyberspace Operations

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/05/expeditionary-cyberspace-operations.html

Cyberspace operations now officially has a physical dimension, meaning that the United States has official military doctrine about cyberattacks that also involve an actual human gaining physical access to a piece of computing infrastructure.

A revised version of Joint Publication 3-12 Cyberspace Operations—published in December 2022 and while unclassified, is only available to those with DoD common access cards, according to a Joint Staff spokesperson—officially provides a definition for “expeditionary cyberspace operations,” which are “[c]yberspace operations that require the deployment of cyberspace forces within the physical domains.”

[…]

“Developing access to targets in or through cyberspace follows a process that can often take significant time. In some cases, remote access is not possible or preferable, and close proximity may be required, using expeditionary [cyber operations],” the joint publication states. “Such operations are key to addressing the challenge of closed networks and other systems that are virtually isolated. Expeditionary CO are often more regionally and tactically focused and can include units of the CMF or special operations forces … If direct access to the target is unavailable or undesired, sometimes a similar or partial effect can be created by indirect access using a related target that has higher-order effects on the desired target.”

[…]

“Allowing them to support [combatant commands] in this way permits faster adaptation to rapidly changing needs and allows threats that initially manifest only in one [area of responsibility] to be mitigated globally in near real time. Likewise, while synchronizing CO missions related to achieving [combatant commander] objectives, some cyberspace capabilities that support this activity may need to be forward-deployed; used in multiple AORs simultaneously; or, for speed in time-critical situations, made available via reachback,” it states. “This might involve augmentation or deployment of cyberspace capabilities to forces already forward or require expeditionary CO by deployment of a fully equipped team of personnel and capabilities.”

On the Poisoning of LLMs

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/05/on-the-poisoning-of-llms.html

Interesting essay on the poisoning of LLMs—ChatGPT in particular:

Given that we’ve known about model poisoning for years, and given the strong incentives the black-hat SEO crowd has to manipulate results, it’s entirely possible that bad actors have been poisoning ChatGPT for months. We don’t know because OpenAI doesn’t talk about their processes, how they validate the prompts they use for training, how they vet their training data set, or how they fine-tune ChatGPT. Their secrecy means we don’t know if ChatGPT has been safely managed.

They’ll also have to update their training data set at some point. They can’t leave their models stuck in 2021 forever.

Once they do update it, we only have their word—pinky-swear promises—that they’ve done a good enough job of filtering out keyword manipulations and other training data attacks, something that the AI researcher El Mahdi El Mhamdi posited is mathematically impossible in a paper he worked on while he was at Google.

How to use managed dedicated IPs for email sending

Post Syndicated from Tyler Holmes original https://aws.amazon.com/blogs/messaging-and-targeting/how-to-use-managed-dedicated-ips-for-email-sending/

Starting to use dedicated IPs has always been a long, complicated process driven by factors such as the large effort to monitor and maintain the IPs and the costs, both in infrastructure and management of IP and Domain reputation. The Dedicated IP (Managed) feature in Amazon SES eliminates much of the complexity of sending email via dedicated IPs and allows you to start sending through dedicated IPs much faster and with less management overhead.

What’s the Difference Between standard dedicated IPs and managed dedicated IPs?

You can use SES for dedicated IP addresses in two ways: standard and managed. Both allow you to lease dedicated IP addresses for an additional fee, but differ in how they’re configured and managed. While there are shared commonalities they each have unique advantages dependent on your use case, see here for a comparison.

Standard dedicated IPs are manually set up and managed in SES. They allow you full control over your sending reputation but require you to fully manage your dedicated IPs, including warming them up, scaling them out, and managing your pools.

Managed dedicated IPs are a quick, and easy, way to start using dedicated IP addresses. These dedicated IP addresses leverage machine learning to remove the need to manage the IP warm-up process. The feature also handles the scaling of your IPs up or down as your volume increases (or decreases) to provide a quick, easy, and cost-efficient way to start using dedicated IP addresses that are managed by SES.

How Does the Managed Dedicated IP Feature Automate IP Warming?

Great deliverability through your dedicated IP address requires that you have a good reputation with the receiving ISPs, also known as a mailbox provider. Mailbox providers will only accept a small volume of email from an IP that they don’t recognize. When you’re first allocated an IP, it’s new and won’t be recognized by the receiving mailbox provider because it doesn’t have any reputation associated with it. In order for an IP’s reputation to be established, it must gradually build trust with receiving mailbox providers—this gradual trust building process is referred to as warming-up. Adding to the complexity is that each mailbox provider has their own concept of warming, accepting varying volumes of email as you work through the warm up process.

The concept of IP warming has always been a misnomer, with customers thinking that once their IP is “warm” that it stays that way when in reality the process is an ongoing one, fluctuating as your recipient domain mix changes and your volume changes. Ensuring that you have the best deliverability when sending via dedicated IPs requires monitoring more than just recipient engagement rates (opens, clicks, bounces, complaints, opt-ins, etc.), you also need to manage volume per mailbox provider. Understanding the volumes that recipient mailbox providers will accept is very difficult if not impossible for senders using standard Dedicated IPs. Managing this aspect of the warm up creates risk for sending too little, meaning warm-up takes longer, or too much, which means receiving mailbox providers may throttle, reduce IP reputation, or even filter out email being sent by an IP that is not properly warming up.

This process is a costly, risky, and time consuming one that can be eliminated using the managed feature. Managed dedicated IPs will automatically apportion the right amount of traffic per mailbox provider to your dedicated IPs and any leftover email volume is sent over the shared network of IPs, allowing you to send as you normally would. As time goes on, the proportion of email traffic being sent over your dedicated IPs increases until they are warm, at which point all of your emails will be sent through your dedicated IPs. In later stages, any sending that is in excess of your normal patterns is proactively queued to ensure the best deliverability to each mailbox provider.

As an example, if you’ve been sending all your traffic to Gmail, the IP addresses are considered warmed up only for Gmail and cold for other mailbox providers. If your customer domain mix changes and includes a large proportion of email sends to Hotmail, SES ramps up traffic slowly for Hotmail as the IP addresses are not warmed up yet while continuing to deliver all the traffic to Gmail via your dedicated IPs. The warmup adjustment is adaptive and is based on your actual sending patterns.

The managed feature is great for those that prioritize and want to be in complete control of their reputation while not wanting to spend the time and effort to manage the warm-up process or the scaling of IPs as your volume grows. A full breakdown of the use cases that are a good fit for the managed feature can be found here

How to Configure Managed Pools and Configuration Sets

Enabling managed dedicated IPs can be configured in just a few steps and can be done either from the console or programmatically. The first step is to create a managed IP pool, then the managed dedicated IPs feature will determine how many dedicated IPs you require based on your sending patterns, provision them for you, and then manage how they scale based on your sending requirements. Note that this process is not instantaneous, dependent on your sending patterns it may take more or less time for the dedicated IPs to be provisioned, you need to have consistent email volume coming from your account in order for the feature to provision the correct number of IPs.

Once enabled, you can utilize managed dedicated IPs in your email sending by associating the managed IP pool with a configuration set, and then specifying that configuration set when sending email. The configuration set can also be applied to a sending identity by using a default configuration set, which can simplify your sending, as anytime the associated sending identity is used to send email your managed dedicated IPs will be used.

Instructions

Configure Via The Console

To enable Dedicated IPs (Managed) via the Amazon SES console:

  • Sign in to the AWS Management Console and open the Amazon SES console at https://console.aws.amazon.com/ses/.
  • In the left navigation pane, choose Dedicated IPs.
  • Do one of the following (Note: You will begin to incur charges after creating a Dedicated IPs (Managed) pool below)
    • If you don’t have existing dedicated IPs in your account:
      • The Dedicated IPs onboarding page is displayed. In the Dedicated IPs (Managed) overview panel, choose Enable dedicated IPs. The Create IP Pool page opens.
    • If you have existing dedicated IPs in your account:
      • Select the Managed IP pools tab on the Dedicated IPs page.
      • In the All Dedicated IP (managed) pools panel, choose Create Managed IP pool. The Create IP Pool page opens.
  • In the Pool details panel,
    • Choose Managed (auto managed) in the Scaling mode field.
    • Enter a name for your managed pool in the IP pool name field.
    • Note
      • The IP pool name must be unique. It can’t be a duplicate of a standard dedicated IP pool name in your account.
      • You can have a mix of up to 50 pools split between both Standard and Dedicated IPs (Managed) per AWS Region in your account.
  • (Optional) You can associate this managed IP pool with a configuration set by choosing one from the dropdown list in the Configuration sets field.
    • Note
      • If you choose a configuration set that’s already associated with an IP pool, it will become associated with this managed pool, and no longer be associated with the previous pool.
      • To add or remove associated configuration sets after this managed pool is created, edit the configuration set’s Sending IP pool parameter in the General details panel.
      • If you haven’t created any configuration sets yet, see Using configuration sets in Amazon SES.
  • (Optional) You can add one or more Tags to your IP pool by including a tag key and an optional value for the key.
    • Choose Add new tag and enter the Key. You can also add an optional Value for the tag. You can add up to 50 tags, if you make a mistake, choose Remove.
    • To add the tags, choose Save changes. After you create the pool, you can add, remove, or edit tags by selecting the managed pool and choosing Edit.
  • Select Create pool.
    • Note
      • After you create a managed IP pool, it can’t be converted to a standard IP pool.
      • When using Dedicated IPs (Managed), you can’t have more than 10,000 sending identities (domains and email addresses, in any combination) per AWS Region in your account.
  • After you create your managed IP pool, a link will automatically be generated in the CloudWatch metrics column in the All Dedicated IPs (Managed) pools table in the SES console, that when selected, will open the Amazon CloudWatch console and display your sending reputation at an effective daily rate with specific mailbox providers for the managed pool using the following metrics:


Metric Description
1 Available24HourSend Indicates how  much volume the managed pool has available to send towards a specific mailbox provider.
2 SentLast24Hours Indicates how  much volume of email has been sent through the managed pool by dedicated IPs  towards a specific mailbox provider.

You can also track the managed pool’s sending performance by using event publishing.

Configure VIA The API

You can configure your Managed Dedicated IP Pool through the API as well. A dedicated pool can be specified to be managed by setting the scaling-mode to “MANAGED” when creating the dedicated pool.

Configure Via The CLI

You can configure your SES resources through the CLI. A dedicated pool can be specified to be managed by setting the —scaling-mode MANAGED parameter when creating the dedicated pool.

  • # Specify which AWS region to use
    • export AWS_DEFAULT_REGION=’us-east-1′
  • # Create a managed dedicated pool
    • aws sesv2 create-dedicated-ip-pool —pool-name dedicated1 —scaling-mode MANAGED
  • # Create a configuration set that that will send through the dedicated pool
    • aws sesv2 create-configuration-set —configuration-set-name cs_dedicated1 —delivery-options SendingPoolName=dedicated1
  • # Configure the configuration set as the default for your sending identity
    • aws sesv2 put-email-identity-configuration-set-attributes —email-identity {{YOUR-SENDING-IDENTITY-HERE}} —configuration-set-name cs_dedicated1
  • # Send SES email through the API or SMTP without requiring any code changes. Emails will # be sent out through the dedicated pool.
    • aws sesv2 send-email –from-email-address “{YOUR-SENDING-IDENTITY-HERE}}” –destination “[email protected]” —content ‘{“Simple”: {“Subject”: {“Data”: “Sent from a Dedicated IP Managed pool”},”Body”: {“Text”: {“Data”: “Hello”}}}}’

Monitoring

We recommend customers onboard to event destinations and delivery delay events to more accurately track the sending performance of their dedicated sending.

Conclusion

In this blog post we explained the benefits of sending via a Dedicated IPs (Managed) feature as well as how to configure and begin sending through a Managed Dedicated IP. Dedicated IPs (Managed) pricing can be reviewed at the pricing page for SES here.

Indiana, Iowa, and Tennessee Pass Comprehensive Privacy Laws

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/05/indiana-iowa-and-tennessee-pass-comprehensive-privacy-laws.html

It’s been a big month for US data privacy. Indiana, Iowa, and Tennessee all passed state privacy laws, bringing the total number of states with a privacy law up to eight. No private right of action in any of those, which means it’s up to the states to enforce the laws.

Reserving EC2 Capacity across Availability Zones by utilizing On Demand Capacity Reservations (ODCRs)

Post Syndicated from Sheila Busser original https://aws.amazon.com/blogs/compute/reserving-ec2-capacity-across-availability-zones-by-utilizing-on-demand-capacity-reservations-odcrs/

This post is written by Johan Hedlund, Senior Solutions Architect, Enterprise PUMA.

Many customers have successfully migrated business critical legacy workloads to AWS, utilizing services such as Amazon Elastic Compute Cloud (Amazon EC2), Auto Scaling Groups (ASGs), as well as the use of Multiple Availability Zones (AZs), Regions for Business Continuity, and High Availability.

These critical applications require increased levels of availability to meet strict business Service Level Agreements (SLAs), even in extreme scenarios such as when EC2 functionality is impaired (see Advanced Multi-AZ Resilience Patterns for examples). Following AWS best practices such as architecting for flexibility will help here, but for some more rigid designs there can still be challenges around EC2 instance availability.

In this post, I detail an approach for Reserving Capacity for this type of scenario to mitigate the risk of the instance type(s) that your application needs being unavailable, including code for building it and ways of testing it.

Baseline: Multi-AZ application with restrictive instance needs

To focus on the problem of Capacity Reservation, our reference architecture is a simple horizontally scalable monolith. This consists of a single executable running across multiple instances as a cluster in an Auto Scaling group across three AZs for High Availability.

Architecture diagram featuring an Auto Scaling Group spanning three Availability Zones within one Region for high availability.

The application in this example is both business critical and memory intensive. It needs six r6i.4xlarge instances to meet the required specifications. R6i has been chosen to meet the required memory to vCPU requirements.

The third-party application we need to run, has a significant license cost, so we want to optimize our workload to make sure we run only the minimally required number of instances for the shortest amount of time.

The application should be resilient to issues in a single AZ. In the case of multi-AZ impact, it should failover to Disaster Recovery (DR) in an alternate Region, where service level objectives are instituted to return operations to defined parameters. But this is outside the scope for this post.

The problem: capacity during AZ failover

In this solution, the Auto Scaling Group automatically balances its instances across the selected AZs, providing a layer of resilience in the event of a disruption in a single AZ. However, this hinges on those instances being available for use in the Amazon EC2 capacity pools. The criticality of our application comes with SLAs which dictate that even the very low likelihood of instance types being unavailable in AWS must be mitigated.

The solution: Reserving Capacity

There are 2 main ways of Reserving Capacity for this scenario: (a) Running extra capacity 24/7, (b) On Demand Capacity Reservations (ODCRs).

In the past, another recommendation would have been to utilize Zonal Reserved Instances (Non Zonal will not Reserve Capacity). But although Zonal Reserved Instances do provide similar functionality as On Demand Capacity Reservations combined with Savings Plans, they do so in a less flexible way. Therefore, the recommendation from AWS is now to instead use On Demand Capacity Reservations in combination with Savings Plans for scenarios where Capacity Reservation is required.

The TCO impact of the licensing situation rules out the first of the two valid options. Merely keeping the spare capacity up and running all the time also doesn’t cover the scenario in which an instance needs to be stopped and started, for example for maintenance or patching. Without Capacity Reservation, there is a theoretical possibility that that instance type would not be available to start up again.

This leads us to the second option: On Demand Capacity Reservations.

How much capacity to reserve?

Our failure scenario is when functionality in one AZ is impaired and the Auto Scaling Group must shift its instances to the remaining AZs while maintaining the total number of instances. With a minimum requirement of six instances, this means that we need 6/2 = 3 instances worth of Reserved Capacity in each AZ (as we can’t know in advance which one will be affected).

Illustration of number of instances required per Availability Zone, in order to keep the total number of instances at six when one Availability Zone is removed. When using three AZs there are two instances per AZ. When using two AZs there are three instances per AZ.

Spinning up the solution

If you want to get hands-on experience with On Demand Capacity Reservations, refer to this CloudFormation template and its accompanying README file for details on how to spin up the solution that we’re using. The README also contains more information about the Stack architecture. Upon successful creation, you have the following architecture running in your account.

Architecture diagram featuring adding a Resource Group of On Demand Capacity Reservations with 3 On Demand Capacity Reservations per Availability Zone.

Note that the default instance type for the AWS CloudFormation stack has been downgraded to t2.micro to keep our experiment within the AWS Free Tier.

Testing the solution

Now we have a fully functioning solution with Reserved Capacity dedicated to this specific Auto Scaling Group. However, we haven’t tested it yet.

The tests utilize the AWS Command Line Interface (AWS CLI), which we execute using AWS CloudShell.

To interact with the resources created by CloudFormation, we need some names and IDs that have been collected in the “Outputs” section of the stack. These can be accessed from the console in a tab under the Stack that you have created.

Example of outputs from running the CloudFormation stack. AutoScalingGroupName, SubnetForManuallyAddedInstance, and SubnetsToKeepWhenDroppingASGAZ.

We set these as variables for easy access later (replace the values with the values from your stack):

export AUTOSCALING_GROUP_NAME=ASGWithODCRs-CapacityBackedASG-13IZJWXF9QV8E
export SUBNET_FOR_MANUALLY_ADDED_INSTANCE=subnet-03045a72a6328ef72
export SUBNETS_TO_KEEP=subnet-03045a72a6328ef72,subnet-0fd00353b8a42f251

How does the solution react to scaling out the Auto Scaling Group beyond the Capacity Reservation?

First, let’s look at what happens if the Auto Scaling Group wants to Scale Out. Our requirements state that we should have a minimum of six instances running at any one time. But the solution should still adapt to increased load. Before knowing anything about how this works in AWS, imagine two scenarios:

  1. The Auto Scaling Group can scale out to a total of nine instances, as that’s how many On Demand Capacity Reservations we have. But it can’t go beyond that even if there is On Demand capacity available.
  2. The Auto Scaling Group can scale just as much as it could when On Demand Capacity Reservations weren’t used, and it continues to launch unreserved instances when the On Demand Capacity Reservations run out (assuming that capacity is in fact available, which is why we have the On Demand Capacity Reservations in the first place).

The instances section of the Amazon EC2 Management Console can be used to show our existing Capacity Reservations, as created by the CloudFormation stack.

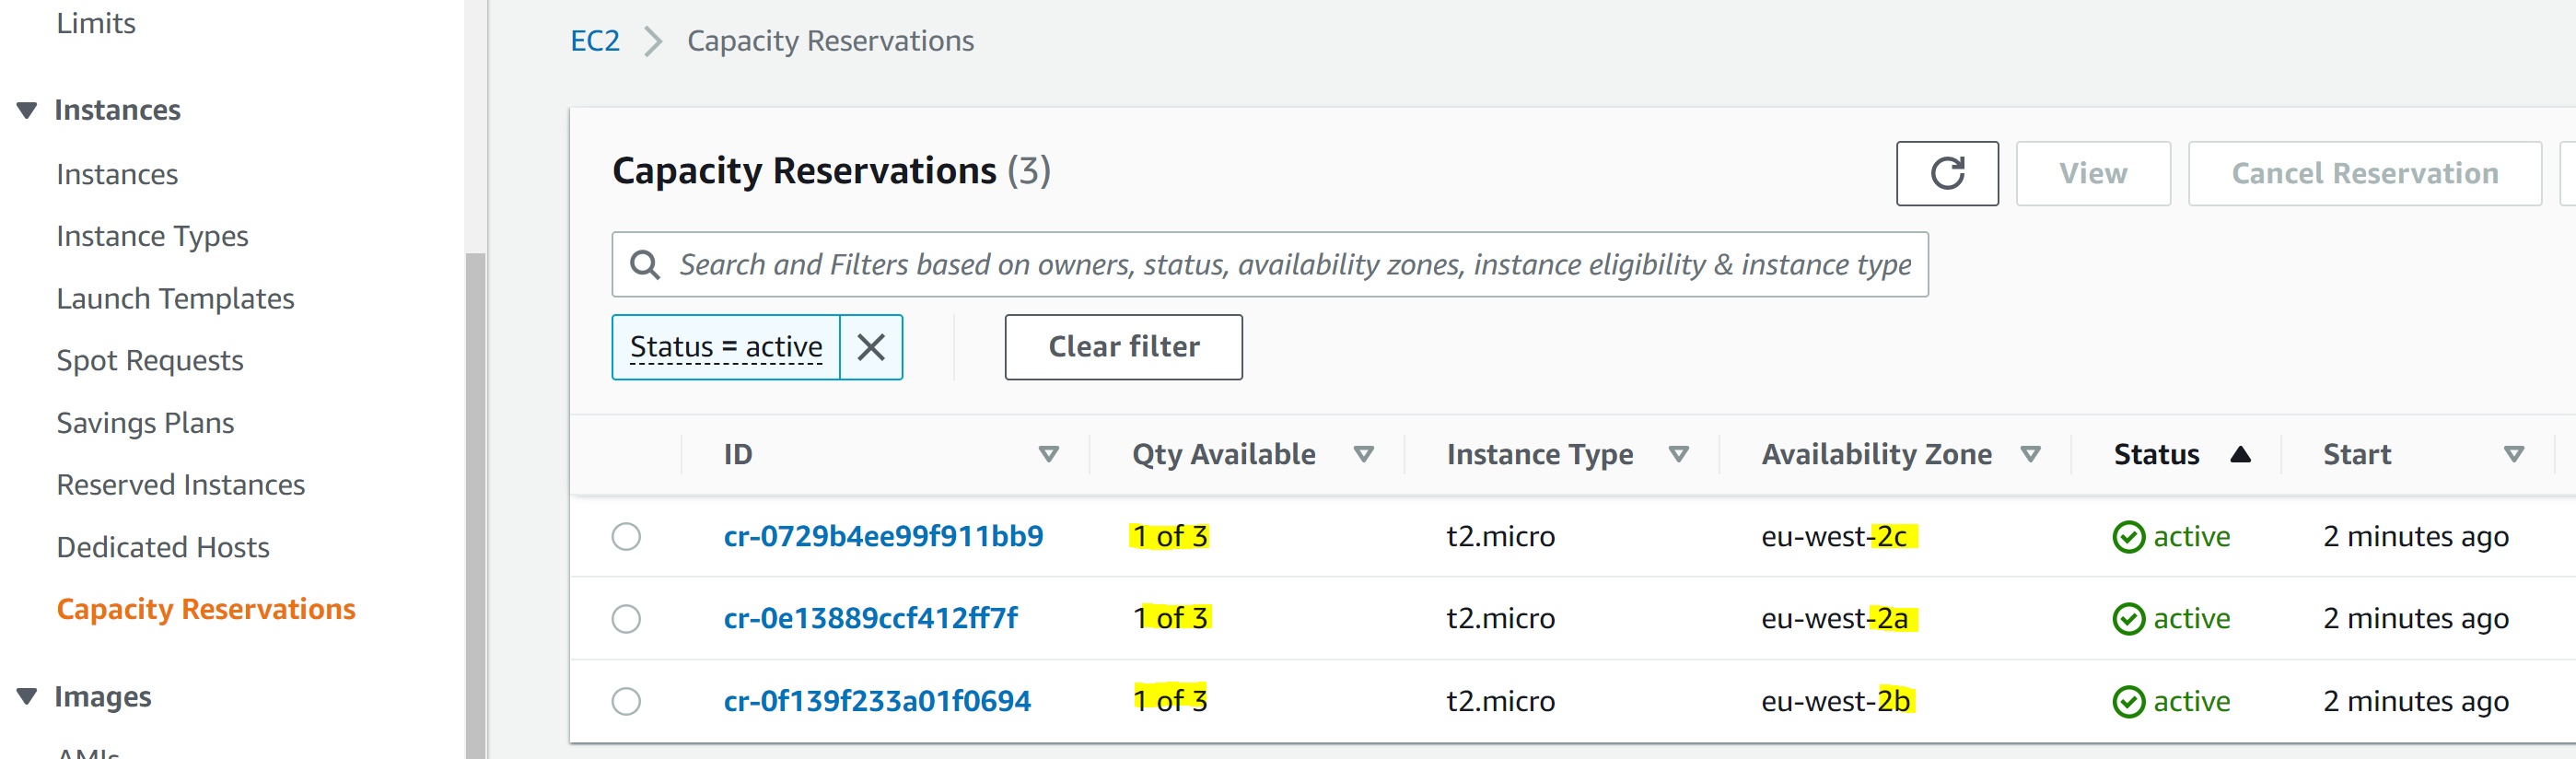
Listing of consumed Capacity Reservations across the three Availability Zones, showing two used per Availability Zone.

As expected, this shows that we are currently using six out of our nine On Demand Capacity Reservations, with two in each AZ.

Now let’s scale out our Auto Scaling Group to 12, thus using up all On Demand Capacity Reservations in each AZ, as well as requesting one extra Instance per AZ.

aws autoscaling set-desired-capacity \
--auto-scaling-group-name $AUTOSCALING_GROUP_NAME \
--desired-capacity 12

The Auto Scaling Group now has the desired Capacity of 12:

Group details of the Auto Scaling Group, showing that Desired Capacity is set to 12.

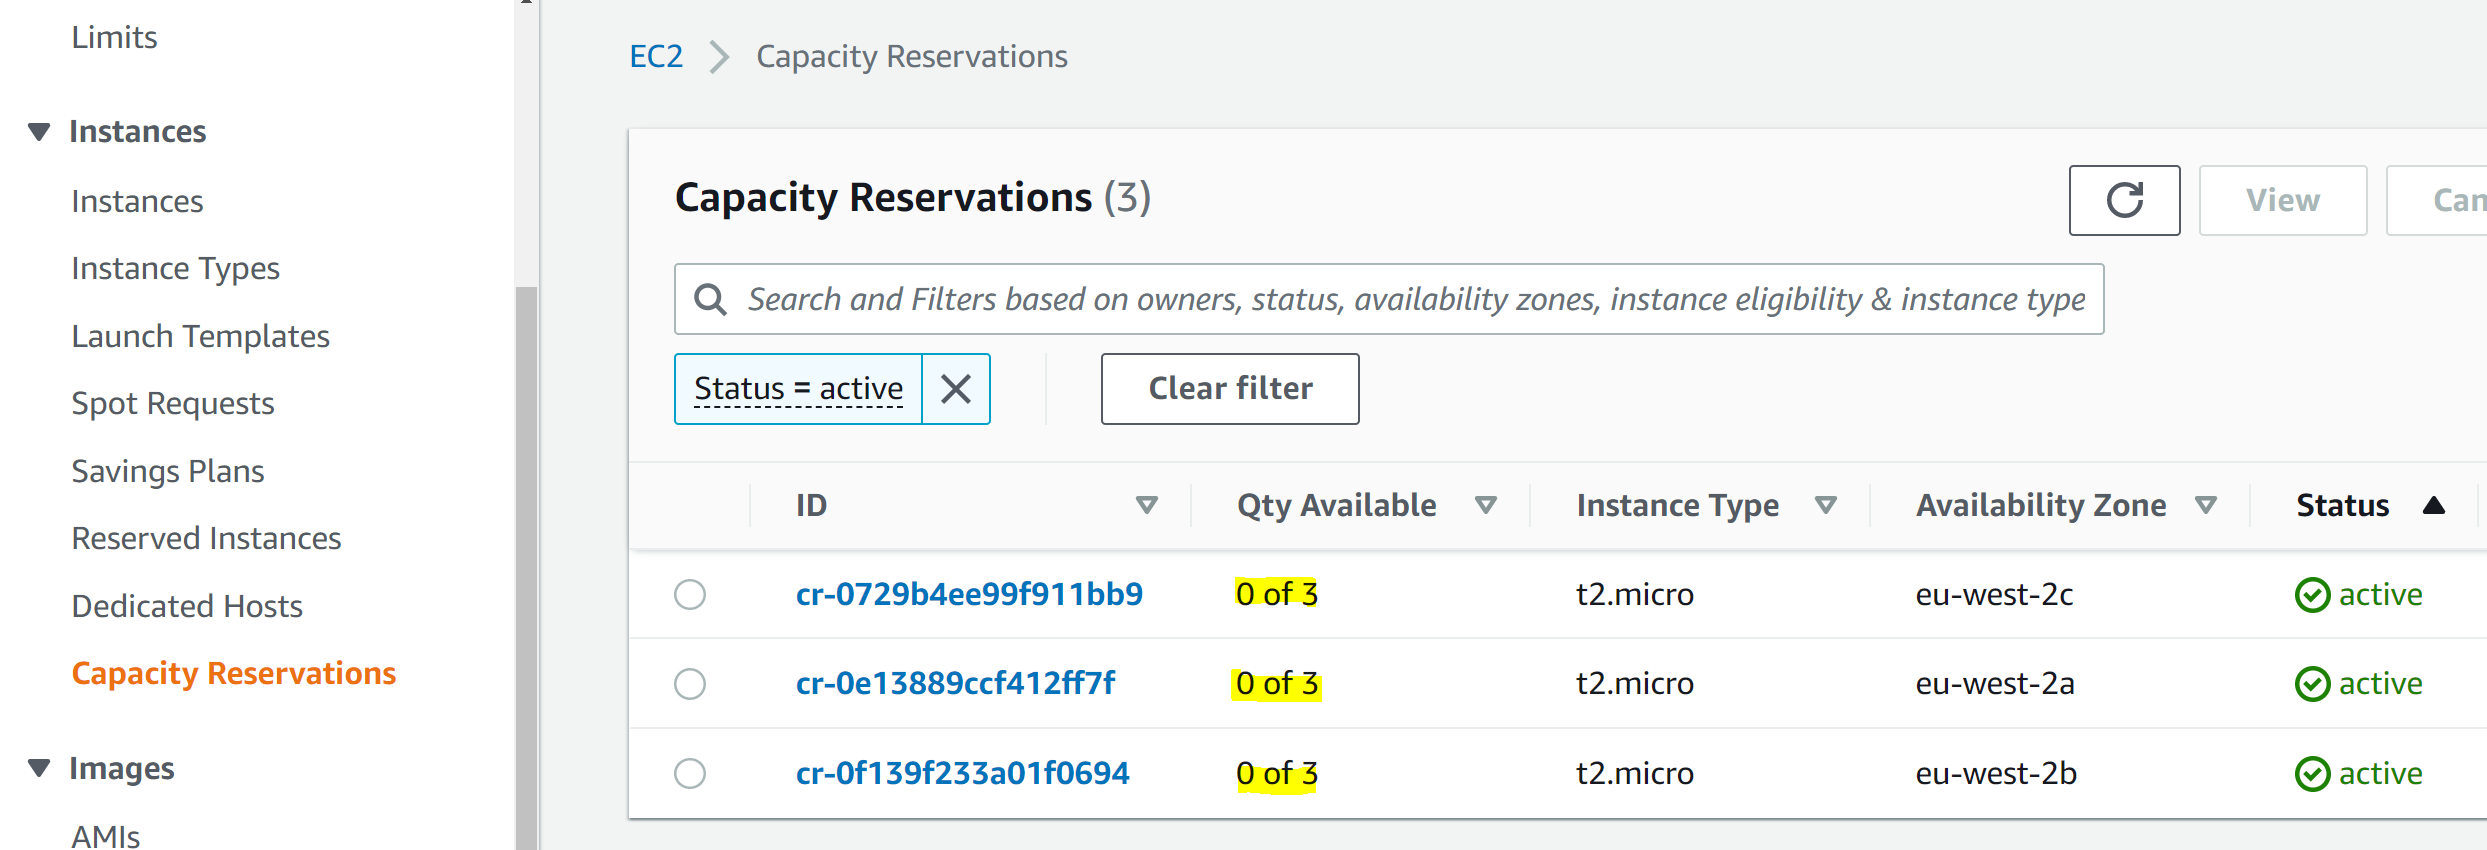
And in the Capacity Reservation screen we can see that all our On Demand Capacity Reservations have been used up:

Listing of consumed Capacity Reservations across the three Availability Zones, showing that all nine On Demand Capacity Reservations are used.

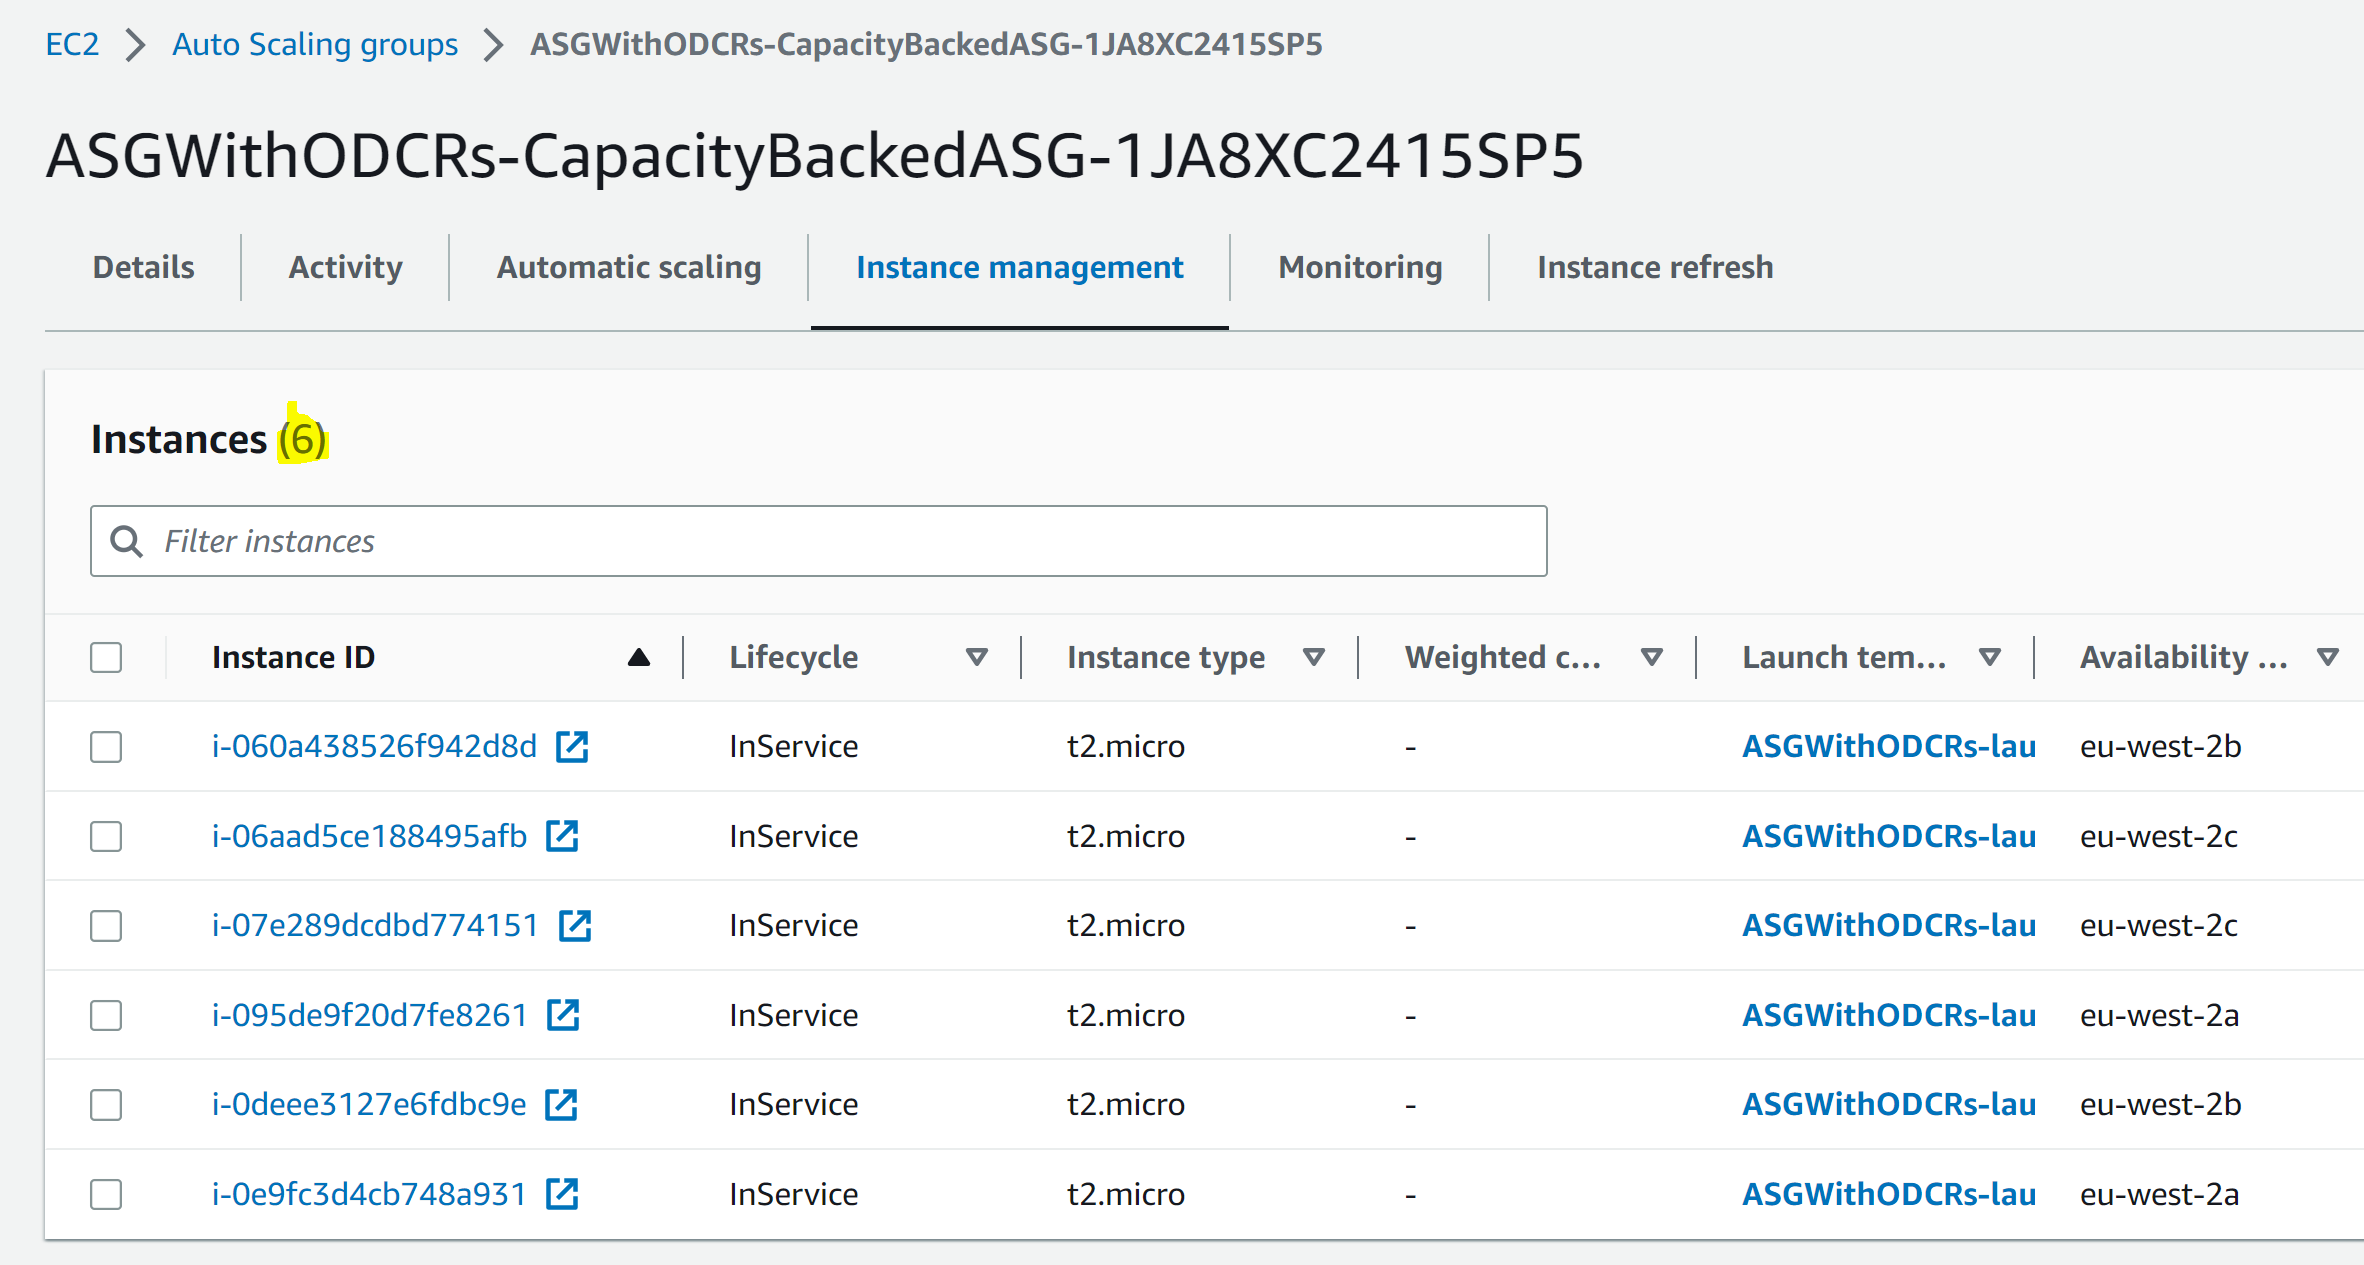
In the Auto Scaling Group we see that – as expected – we weren’t restricted to nine instances. Instead, the Auto Scaling Group fell back on launching unreserved instances when our On Demand Capacity Reservations ran out:

Listing of Instances in the Auto Scaling Group, showing that the total count is 12.

How does the solution react to adding a matching instance outside the Auto Scaling Group?

But what if someone else/another process in the account starts an EC2 instance of the same type for which we have the On Demand Capacity Reservations? Won’t they get that Reservation, and our Auto Scaling Group will be left short of its three instances per AZ, which would mean that we won’t have enough reservations for our minimum of six instances in case there are issues with an AZ?

This all comes down to the type of On Demand Capacity Reservation that we have created, or the “Eligibility”. Looking at our Capacity Reservations, we can see that they are all of the “targeted” type. This means that they are only used if explicitly referenced, like we’re doing in our Target Group for the Auto Scaling Group.

Listing of existing Capacity Reservations, showing that they are of the targeted type.

It’s time to prove that. First, we scale in our Auto Scaling Group so that only six instances are used, resulting in there being one unused capacity reservation in each AZ. Then, we try to add an EC2 instance manually, outside the target group.

First, scale in the Auto Scaling Group:

aws autoscaling set-desired-capacity \
--auto-scaling-group-name $AUTOSCALING_GROUP_NAME \
--desired-capacity 6

Listing of consumed Capacity Reservations across the three Availability Zones, showing two used reservations per Availability Zone.

Listing of Instances in the Auto Scaling Group, showing that the total count is six

Then, spin up the new instance, and save its ID for later when we clean up:

export MANUALLY_CREATED_INSTANCE_ID=$(aws ec2 run-instances \
--image-id resolve:ssm:/aws/service/ami-amazon-linux-latest/amzn2-ami-hvm-x86_64-gp2 \
--instance-type t2.micro \
--subnet-id $SUBNET_FOR_MANUALLY_ADDED_INSTANCE \
--query 'Instances[0].InstanceId' --output text) 

Listing of the newly created instance, showing that it is running.

We still have the three unutilized On Demand Capacity Reservations, as expected, proving that the On Demand Capacity Reservations with the “targeted” eligibility only get used when explicitly referenced:

Listing of consumed Capacity Reservations across the three Availability Zones, showing two used reservations per Availability Zone.

How does the solution react to an AZ being removed?

Now we’re comfortable that the Auto Scaling Group can grow beyond the On Demand Capacity Reservations if needed, as long as there is capacity, and that other EC2 instances in our account won’t use the On Demand Capacity Reservations specifically purchased for the Auto Scaling Group. It’s time for the big test. How does it all behave when an AZ becomes unavailable?

For our purposes, we can simulate this scenario by changing the Auto Scaling Group to be across two AZs instead of the original three.

First, we scale out to seven instances so that we can see the impact of overflow outside the On Demand Capacity Reservations when we subsequently remove one AZ:

aws autoscaling set-desired-capacity \
--auto-scaling-group-name $AUTOSCALING_GROUP_NAME \
--desired-capacity 7

Then, we change the Auto Scaling Group to only cover two AZs:

aws autoscaling update-auto-scaling-group \
--auto-scaling-group-name $AUTOSCALING_GROUP_NAME \
--vpc-zone-identifier $SUBNETS_TO_KEEP

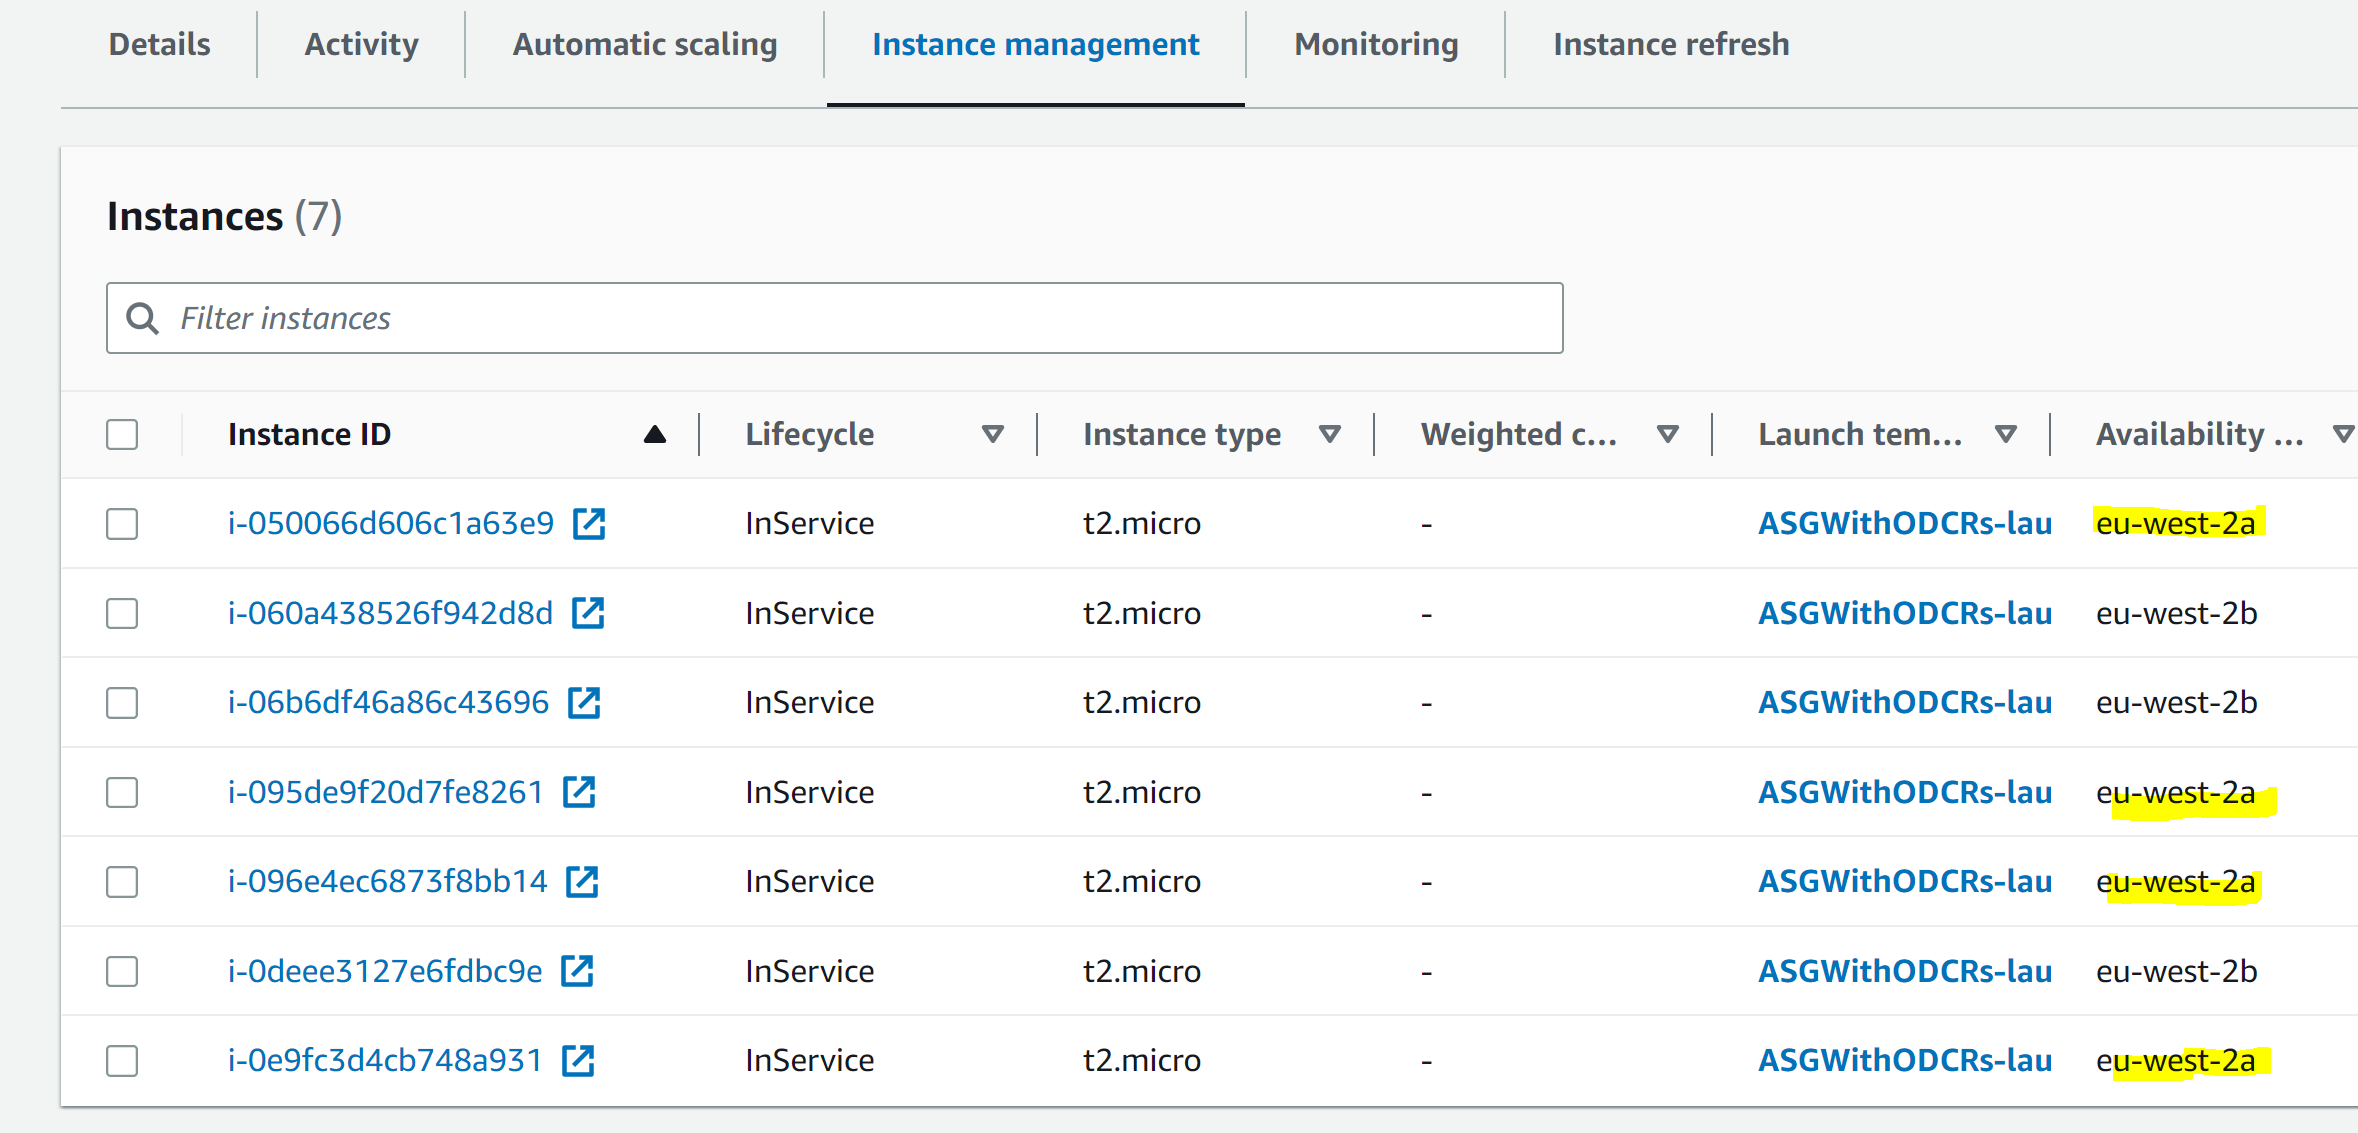
Give it some time, and we see that the Auto Scaling Group is now spread across two AZs, On Demand Capacity Reservations cover the minimum six instances as per our requirements, and the rest is handled by instances without Capacity Reservation:

Network details for the Auto Scaling Group, showing that it is configured for two Availability Zones.

Listing of consumed Capacity Reservations across the three Availability Zones, showing two Availability Zones using three On Demand Capacity Reservations each, with the third Availability Zone not using any of its On Demand Capacity Reservations.

Listing of Instances in the Auto Scaling Group, showing that there are 4 instances in the eu-west-2a Availability Zone.

Cleanup

It’s time to clean up, as those Instances and On Demand Capacity Reservations come at a cost!

  1. First, remove the EC2 instance that we made:
    aws ec2 terminate-instances --instance-ids $MANUALLY_CREATED_INSTANCE_ID
  2. Then, delete the CloudFormation stack.

Conclusion

Using a combination of Auto Scaling Groups, Resource Groups, and On Demand Capacity Reservations (ODCRs), we have built a solution that provides High Availability backed by reserved capacity, for those types of workloads where the requirements for availability in the case of an AZ becoming temporarily unavailable outweigh the increased cost of reserving capacity, and where the best practices for architecting for flexibility cannot be followed due to limitations on applicable architectures.

We have tested the solution and confirmed that the Auto Scaling Group falls back on using unreserved capacity when the On Demand Capacity Reservations are exhausted. Moreover, we confirmed that targeted On Demand Capacity Reservations won’t risk getting accidentally used by other solutions in our account.

Now it’s time for you to try it yourself! Download the IaC template and give it a try! And if you are planning on using On Demand Capacity Reservations, then don’t forget to look into Savings Plans, as they significantly reduce the cost of that Reserved Capacity..

Credible Handwriting Machine

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/05/credible-handwriting-machine.html

In case you don’t have enough to worry about, someone has built a credible handwriting machine:

This is still a work in progress, but the project seeks to solve one of the biggest problems with other homework machines, such as this one that I covered a few months ago after it blew up on social media. The problem with most homework machines is that they’re too perfect. Not only is their content output too well-written for most students, but they also have perfect grammar and punctuation ­ something even we professional writers fail to consistently achieve. Most importantly, the machine’s “handwriting” is too consistent. Humans always include small variations in their writing, no matter how honed their penmanship.

Devadath is on a quest to fix the issue with perfect penmanship by making his machine mimic human handwriting. Even better, it will reflect the handwriting of its specific user so that AI-written submissions match those written by the student themselves.

Like other machines, this starts with asking ChatGPT to write an essay based on the assignment prompt. That generates a chunk of text, which would normally be stylized with a script-style font and then output as g-code for a pen plotter. But instead, Devadeth created custom software that records examples of the user’s own handwriting. The software then uses that as a font, with small random variations, to create a document image that looks like it was actually handwritten.

Watch the video.

My guess is that this is another detection/detection avoidance arms race.

Preparing young children for a digital world | Hello World #21

Post Syndicated from Sway Grantham original https://www.raspberrypi.org/blog/preparing-young-children-digital-world-hello-world-21/

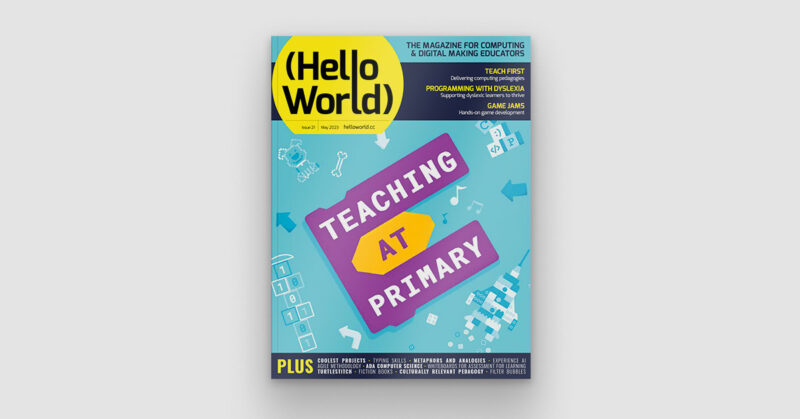
How do we teach our youngest learners digital and computing skills? Hello World‘s issue 21 will focus on this question and all things primary school computing education. We’re excited to share this new issue with you on Tuesday 30 May. Today we’re giving you a taste by sharing an article from it, written by our own Sway Grantham.

Cover of Hello World issue 21.

How are you preparing young children for a world filled with digital technology? Technology use of our youngest learners is a hotly debated topic. From governments to parents and from learning outcomes to screen-time rules, everyone has an opinion on the ‘right’ approach. Meanwhile, many young children encounter digital technology as a part of their world at home. For example in the UK, 87 percent of 3- to 4-year-olds and 93 percent of 5- to 7-year-olds went online at home in 2023. Schools should be no different.

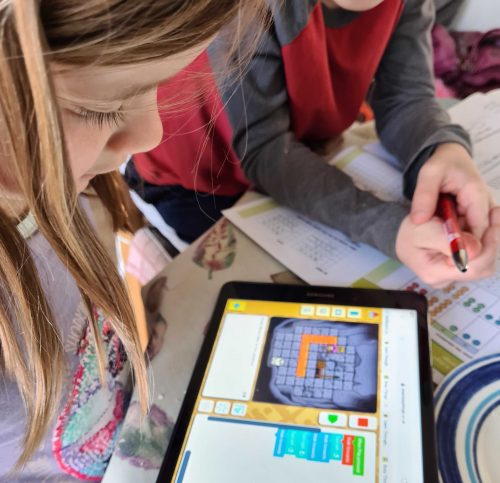
A girl doing digital making on a tablet

As educators, we have a responsibility to prepare learners for life in a digital world. We want them to understand its uses, to be aware of its risks, and to have access to the wide range of experiences unavailable without it. And we especially need to consider the children who do not encounter technology at home. Education should be a great equaliser, so we need to ensure all our youngest learners have access to the skills they need to realise their full potential.

Exploring technology and the world

A major aspect of early-years or kindergarten education is about learners sharing their world with each other and discovering that everyone has different experiences and does things in their own way. Using digital technology is no different.

Allowing learners to share their experiences of using digital technology both accepts the central role of technology in our lives today and also introduces them to its broader uses in helping people to learn, talk to others, have fun, and do work. At home, many young learners may use technology to do just one of these things. Expanding their use of technology can encourage them to explore a wider range of skills and to see technology differently.

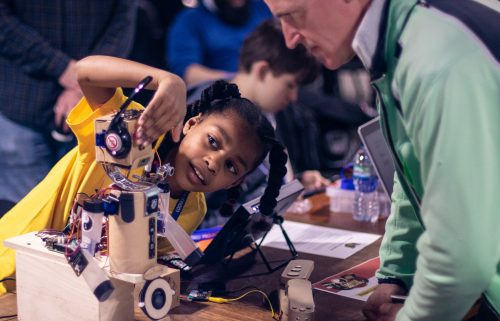
A girl shows off a robot she has built.

In their classroom environment, these explorations can first take place as part of the roleplay area of a classroom, where learners can use toys to show how they have seen people use technology. It may seem counterintuitive that play-based use of non-digital toys can contribute to reducing the digital divide, but if you don’t know what technology can do, how can you go about learning to use it? There is also a range of digital roleplay apps (such as the Toca Boca apps) that allow learners to recreate their experiences of real-world situations, such as visiting the hospital, a hair salon, or an office. Such apps are great tools for extending roleplay areas beyond the resources you already have.

Another aspect of a child’s learning that technology can facilitate is their understanding of the world beyond their local community. Technology allows learners to explore the wider world and follow their interests in ways that are otherwise largely inaccessible. For example:

  • Using virtual reality apps, such as Expeditions Pro, which lets learners explore Antarctica or even the bottom of the ocean
  • Using augmented reality apps, such as Octagon Studio’s 4D+ cards, which make sea creatures and other animals pop out of learners’ screens
  • Doing a joint project with a class of children in another country, where learners blog or share ‘email’ with each other

Each of these opportunities gives children a richer understanding of the world while they use technology in meaningful ways.

Technology as a learning tool

Beyond helping children to better understand our world, technology offers opportunities to be expressive and imaginative. For example, alongside your classroom art activities, how about using an app like Draw & Tell, which helps learners draw pictures and then record themselves explaining what they are drawing? Or what about using filters on photographs to create artistic portraits of themselves or their favourite toys? Digital technology should be part of the range of tools learners can access for creative play and expression, particularly where it offers opportunities that analogue tools don’t.

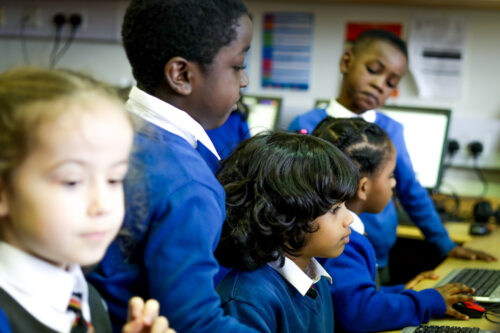
Young learners at computers in a classroom.

Using technology is also invaluable for learners who struggle with communication and language skills. When speaking is something you find challenging, it can often be intimidating to talk to others who speak much more confidently. But speaking to a tablet? A tablet only speaks as well as you do. Apps to record sounds and listen back to them are a helpful way for young children to learn about how clear their speech is and practise speech exercises. ChatterPix Kids is a great tool for this. It lets learners take a photo of an object, e.g. their favourite soft toy, and record themselves talking about it. When they play back the recording, the app makes it look like the toy is saying their words. This is a very engaging way for young learners to practise communicating.

Technology is part of young people’s world

No matter how we feel about the role of technology in the lives of young people, it is a part of their world. We need to ensure we are giving all learners opportunities to develop digital skills and understand the role of technology, including how people can use it for social good.

A woman and child follow instructions to build a digital making project at South London Raspberry Jam.

This is not just about preparing them for their computing education (although that’s definitely a bonus!) or about online safety (although this is vital — see my articles in Hello World issue 15 and issue 19 for more about the topic). It’s about their right to be active citizens in the digital world.

So I ask again: how are you preparing young children for a digital world?

Subscribe to the Hello World digital edition for free

The first experiences children have with learning about computing and digital technologies are formative. That’s why primary computing education should be of interest to all educators, no matter what the age of your learners is. This issue covers for example:

And there’s much more besides. So don’t miss out on this upcoming issue of Hello World — subscribe for free today to receive every PDF edition in your inbox on the day of publication.

The post Preparing young children for a digital world | Hello World #21 appeared first on Raspberry Pi Foundation.

Google Is Not Deleting Old YouTube Videos

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/05/google-is-not-deleting-old-youtube-videos.html

Google has backtracked on its plan to delete inactive YouTube videos—at least for now. Of course, it could change its mind anytime it wants.

It would be nice if this would get people to think about the vulnerabilities inherent in letting a for-profit monopoly decide what of human creativity is worth saving.

За руския народ

Post Syndicated from original http://www.gatchev.info/blog/?p=2578

Мисля си за руския народ. Какво отношение заслужава той – днес, по време на агресията на Русия в Украйна?

Уви, днес руският народ масово подкрепя великоруския нацизъм. Да, има руснаци, които му се противопоставят с риск за свободата и живота си, и те заслужават огромно уважение и възхищение. Но те не са мнозинството. А мнозинството е, което прави народа – и заслужава презрение и позор.

Да, може би след 50 или 100 години руският народ ще е така далече от нацизма, както са днес германският и японският народи. Тогава може би ще заслужава отношение като към германците и японците днес. Но сега заслужава каквото заслужават германският и японският народи по времето на Хитлер и Хирохито.

Да, мнозинството руснаци всъщност не са виновни за отровата в главите си. Жертва са на пропагандата, с която биват облъчвани. Затова не бих разстрелял или затворил искрен поддръжник на руския нацизъм. (Руската агентура, която пропагандира рашизма знаейки, че е вид нацизъм, за мен заслужава същото, каквото заслужиха служителите на Гьобелс в Германия.) Но с много малко изключения се отнасям към искрените поддръжници на рашизма, и в Русия и у нас, с презрението, което каузата им заслужава. Без това те нямат как да осъзнаят, че подкрепят античовечност, и да я отхвърлят. А не я ли отхвърлят, ще продължат да са гранати, които стоят на масата и чакат някой да ги грабне и запрати по някого.

Това е моята позиция.

Friday Squid Blogging: Peruvian Squid-Fishing Regulation Drives Chinese Fleets Away

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/05/friday-squid-blogging-peruvian-squid-fishing-regulation-drives-chinese-fleets-away.html

A Peruvian oversight law has the opposite effect:

Peru in 2020 began requiring any foreign fishing boat entering its ports to use a vessel monitoring system allowing its activities to be tracked in real time 24 hours a day. The equipment, which tracks a vessel’s geographic position and fishing activity through a proprietary satellite communication system, sought to provide authorities with visibility into several hundred Chinese squid vessels that every year amass off the west coast of South America.

[…]

Instead of increasing oversight, the new Peruvian regulations appear to have driven Chinese ships away from the country’s ports—and kept crews made up of impoverished Filipinos and Indonesians at sea for longer periods, exposing them to abuse, according to new research published by Peruvian fishing consultancy Artisonal.

Two things to note here. One is that the Peruvian law was easy to hack, which China promptly did. The second is that no nation-state has the proper regulatory footprint to manage the world’s oceans. These are global issues, and need global solutions. Of course, our current society is terrible at global solutions—to anything.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

How Cirrusgo enabled rapid resolution with Amazon DevOps Guru

Post Syndicated from Harish Bannai original https://aws.amazon.com/blogs/devops/how-cirrusgo-enabled-rapid-resolution-with-devops-guru/

Image of the Cirrusgo company logo.

In this blog, we will walk through how Cirrusgo used Amazon DevOps Guru for RDS to quickly identify and resolve their operational issue related to database performance and reduce the impact on their business. This capability is offered by Amazon DevOps Guru for RDS which uses machine learning algorithms to help organizations identify and resolve operational issues in their applications and infrastructure.

Challenge:

Knowlegebeam, one of Cirrusgo’s managed service customers, has an e-learning web application that serves as a mission-critical tool for nearly 90,000 teachers. The application tracks daily activities, including teaching and evaluating homework and quizzes submitted by students. Any interruption of the availability of this application causes significant inconvenience to teachers and students, as well as damage to the company’s reputation. Ensuring the continuous and reliable performance of customer workloads is of utmost importance to Cirrusgo.

Identification of Operational issues with Amazon DevOps Guru:

To streamline the troubleshooting process and avoid time-consuming manual analysis of logs, Cirrusgo leveraged the power of Amazon DevOps Guru to monitor Knowledge Beam’s stack. With just a few clicks in the AWS console, Cirrusgo seamlessly enabled DevOps Guru that uses advanced machine learning techniques to analyze Amazon CloudWatch metrics, AWS CloudTrail, and Amazon Relational Database Service (Amazon RDS) Performance Insights. This enables it to quickly identify behaviors that deviate from standard operating patterns and pinpoint the root cause of operational issues.

When users reported difficulty submitting assignments via the e-learning portal, Cirrusgo’s team launched an investigation. The team discovered 4xx and 5xx Amazon Elastic Load Balancing errors in the CloudWatch metrics. There was no additional information available. While examining the load balancer and application logs, the engineers received Amazon DevOps Guru notifications regarding Amazon RDS) replica lag. The team promptly investigated and confirmed the existence of the Amazon RDS replica lag. The team ran commands to stop traffic to the replica instance and shift all traffic to the Amazon RDS primary node. Thanks to DevOps Guru’s insightful recommendations, the team identified and resolved the issue. The team was able to use the root cause of the issue and take additional steps to prevent its recurrence. This included creating an Amazon RDS Read Replica and upgrading the instance type based on the current workload.

Cirrusgo quickly identified and addressed critical operational issues in Knowledge Beam’s application. This enabled them to minimize the immediate impact and enhance their customer’s applications’ future reliability and performance.

“Amazon DevOps Guru was very beneficial that helped us identify incidents in Amazon RDS. It provided useful insights we previously didn’t have, and it helped reduce our mitigation time. We implemented it to some accounts we are managing and are taking advantage”, says Mohammed Douglas Otaibi, Technical Co-Founder of Cirrusgo

Conclusion:

This post highlights how Cirrusgo leveraged Amazon DevOps Guru to identify and quickly address anomalous behavior.

Are you looking for a way to improve the monitoring of your Amazon RDS databases? Look no further than Amazon DevOps Guru. With DevOps Guru’s RDS monitoring capabilities, you can gain deep insights into the performance and health of your databases. This includes automatic anomaly detection, proactive recommendations, and alerts for issues that require your attention.

About the authors:

Harish Bannai

Harish Bannai is a Sr. Technical Account Manager at Amazon Web Services. He holds the AWS Solutions Architect Professional, Developer Associate, Analytics Specialty , AWS Database Specialty and Solutions Architect Professional certifications. He works with enterprise customers providing technical assistance on RDS, Database Migration services operational performance and sharing database best practices.

Adnan Bilwani

Adnan Bilwani is a Sr. Senior Specialist at Amazon Web Services. Lucy focuses on improving application qualification and availability by leveraging AWS DevOps services and tools.

Lucy Hartung

Lucy Hartung is a Senior Specialist at Amazon Web Services. Lucy focuses on improving application qualification and availability by leveraging AWS.