Version
2.0 of Syncthing, a
continuous file synchronization utility, has been released. Notable
changes in 2.0 include multiple connections for synchronizing metadata
and file data, a new logging format, as well as a switch from LevelDB
to SQLite for Syncthing’s backend. This the first release in the 2.0
series, and the release notes advise users to “expect some rough
edges and keep a sense of adventure“.
If you’ve spent any time sourcing, evaluating, or speculating about cloud services in the public sector lately, you’ve likely felt it: the arms race happening in compliance. Courting customers from schools to statehouses to national labs, more and more cloud vendors are racing to pin the next security badge to their lapel—GovRAMP (formerly known as StateRAMP), TX-RAMP, FedRAMP, SOC 2, and on and on.
And while it might feel like a compliance bingo card, there’s real strategy and real consequences behind this sprint. At the heart of it all is the SLED market (state and local government, and education)—a sprawling patchwork of institutions tasked with safeguarding citizen data and taxpayer trust, all while operating with limited resources and infrastructure budgets.
Let’s talk about why this compliance arms race exists, what it means for buyers and vendors alike, and how we at Backblaze are choosing to compete not just with checkboxes, but with character.
Why does SLED even need unified standards?
Public sector IT has long been a security quilt. Some agencies stitched up with advanced defenses, others more… threadbare. While some may have advanced security tooling, a K–12 school district might still be running on legacy systems and duct tape. Yet both manage data that’s increasingly digital, distributed, and vulnerable.
The result? Inconsistent practices and rising risks. Enter: GovRAMP.
What is GovRAMP?
Short for Government Risk and Authorization Management Program, GovRAMP was customized to standardize cloud security for state and local agencies. It’s actually based on the same set of controls for FedRAMP—controls derived from the National Institute of Standards and Technology (NIST) SP 800-53, a catalog of controls for organizations to manage cybersecurity and privacy risk. GovRAMP ensures that even the smallest public institutions can procure secure IT solutions without reinventing the wheel every time.
GovRAMP was originally launched as StateRAMP, but has since grown beyond state lines, evolving into a broader framework adopted by local governments and school systems. Today, it’s a rigorous, independent audit program that holds vendors to a high set of security controls. Translation: If a vendor is GovRAMP-authorized, they’re playing in the big leagues of cloud security.
The alphabet soup of compliance: TX-RAMP, GovRAMP, FedRAMP
If you’re in Texas, you’re probably familiar with TX-RAMP, the state’s specific compliance framework. The good news? GovRAMP and TX-RAMP are closely aligned. At Backblaze, our GovRAMP Progressing Snapshot status qualifies us for TX-RAMP Provisional Authorization as well—one less hurdle for Texas agencies seeking secure, scalable cloud storage.
As for FedRAMP, it remains the gold standard for federal data, but for the vast majority of public sector orgs, including most SLED agencies, it’s simply unnecessary.
How GovRAMP streamlines cloud sourcing
Here’s where the compliance arms race actually makes things easier: Once a vendor is authorized through GovRAMP, SLED buyers can trust that the solution meets certain security standards, saving months of one-off vetting, paperwork, and duplicated audits. In a procurement environment plagued by inefficiency, that’s no small thing.
Especially now, as budgets tighten and AI-driven everything drives demand for flexible infrastructure, reducing sourcing friction matters more than ever.
Going beyond checklists: What buyers should really look for
Checkboxes alone don’t guarantee real-world resilience. Compliance can become its own form of security theater. It looks good on paper but falls short in practice. That’s why buyers should dig deeper.
Look for vendors who not only pass audits but live and breathe their controls. That means going beyond annual assessments and embracing security as a continuous, integrated discipline. The best partners are transparent, proactive, and thoughtful about risk—not just checking boxes, but building real-world resilience. Here are a few signs to look for:
Continuous monitoring and internal audits: They treat compliance as an ongoing process, not a once-a-year scramble.
Clear, accessible documentation: Security policies, certifications, and standardized independent attestations are available (under NDA if needed), not locked in a black box.
Transparent data practices: They’re upfront about where your data lives, who can access it, and what happens in the event of an incident.
Responsive support: You can communicate with real people who understand your risk profile—not just surface-level answers or automated replies.
Affordable recoveries: They don’t make recovering your data prohibitively expensive. Look at their egress policies and price out what it would actually cost to retrieve your data.
When you’re responsible for protecting sensitive data, it’s not enough to be compliant. You need a partner who’s disciplined, trustworthy, and invested in your resilience.
The Backblaze approach: Rigor, transparency, and trust
Pursuing authorizations like GovRAMP and TX-RAMP isn’t easy, but it’s the right thing to do and we’re committed to the process. We believe public sector buyers deserve cloud partners who understand their constraints, meet them where they are, and still bring best-in-class solutions to the table.
But more than that, we’re not stopping at frameworks. Compliance is a floor, not a ceiling. We’ve built our platform on decades of operational rigor and security discipline—not to impress auditors, but to earn your trust. And we’ve structured our products to enable security best practices, not hinder them, including 3x free egress for disaster recovery.
So yes, we’re proudly in the compliance race. But we’re not just chasing badges. We’re building something secure, sustainable, and ready for whatever comes next.
Want to learn more about our GovRAMP journey or how Backblaze supports public sector cloud transformation? Reach out to our Sales team.
The Indico event-management tool has
been in development at CERN for two
decades at this point. The MIT-licensed web application helps organize
conferences, meetings, workshops, and so on; it runs on Python and uses the Flask web framework. Two software engineers on the project, Dominic
Hollis and Tomas Roun, came to EuroPython 2025 in Prague to talk about
Indico, its history, and some metrics about its community. There is a bit of a
connection between Indico and the conference: in 2006 and 2007,
the tool was used to manage EuroPython.
The NSA and GCHQ have jointly published a history of World War II SIGINT: “Secret Messengers: Disseminating SIGINT in the Second World War.” This is the story of the British SLUs (Special Liaison Units) and the American SSOs (Special Security Officers).
Today, we’re officially announcing the AWS Cloud Control API (CCAPI) MCP Server. This MCP server transforms AWS infrastructure management by allowing developers to create, read, update, delete, and list resources using natural language. As part of the awslabs/mcp project, this new and innovative tool serves as a bridge between natural language commands and AWS infrastructure deployment and management. This MCP server is powered by the AWS Cloud Control API – a standardized API that allows CRUDL (Create/Read/Update/Delete/List) operations to be performed against AWS and third party resources using a single endpoint.
Key Features:
Leverages AWS Cloud Control API for CRUDL operations for more than 1,200 AWS resources
Enables LLM-powered agents and developers to manage infrastructure with natural language prompts
Provides the option to output Infrastructure as Code (IaC) templates for infrastructure it will create, allowing to still be used with existing CI/CD pipelines
Integrates with AWS Pricing API to provide cost estimates for the infrastructure it will create
Applies security best practices automatically using Checkov
Why Use CCAPI MCP Server?
Simplified Infrastructure Management: No more wrestling with complex templates or documentation
Increased Developer Productivity: Focus on what you need, not how to configure it
Reduced Learning Curve: Onboard new team members faster with natural language commands
LLM Integration: Perfect companion for AI-assisted development workflows
The CCAPI MCP Server transforms infrastructure management by enabling natural language interactions for AWS resource operations. Bridging natural language commands with AWS infrastructure deployment and management, this MCP Server allows developers to manage cloud infrastructure through conversational inputs such as:
Can you create a new s3 bucket for me?or
Find all of my EC2 instances and tell me which one have an instance type that is not t2.large
This significantly reduces configuration overhead and accelerates onboarding for new team members, directly translates developer intent into cloud infrastructure.
Let’s see it in action.
Creating and Managing Cloud Infrastructure
Prerequisites
uv package manager installed
Python 3.x.x installed
AWS credentials with appropriate permissions. The MCP server supports multiple ways to define these credentials. See the MCP documentation for more information. Using dynamic credentials such as one provided via SSO is recommended. For more information on configuring AWS credentials, see the AWS CLI documentation.
An MCP Host application installed that supports MCP Clients and MCP Servers (e.g. Amazon Q Developer, Claude Desktop, Cursor, etc.). To follow this blog install Amazon Q Developer for CLI (CLI) as described in the installation instructions
Integration with Developer Tools
To start using the CCAPI MCP server, you will need to set up your server configuration which is typically in a file named mcp.json. For this blog we will focus on using the CCAPI MCP server with Amazon Q Developer. Note that for other MCP Host applications the path to the mcp configuration file may differ. You will need to create the file if it does not already exist in the directory.
1. Global Configuration: ~/.aws/amazon/mcp.json – Applies to all workspaces
2. Workspace Configuration: .amazonq/mcp.json – Specific to the current workspace
Ensure you correctly set your AWS credentials in the MCP server config. It is essential that you properly configure these credentials, as the MCP server uses their associated permissions when invoking the AWS Cloud Control API for CRUDL operations in your AWS account. The server supports multiple methods of consuming these credentials such as AWS profiles, Environment Variables, SSO tokens, etc. You can see some of this in the aws_client.py file. See these docs on using named profiles for more information.
Read Only Mode
If you would like to prevent the MCP server from performing mutating actions (e.g. Create/Update/Delete Resource), you can specify the --readonly flag as demonstrated below:
More information on the configuration and tools the CCAPI MCP server provides can be found in the AWS CloudFormation MCP Server documentation.
Security Considerations
Ensure the IAM credentials include permissions for Cloud Control API actions (List, Get, Create, Update, Delete). See the AWS CCAPI API documentation for more info
Consider running in read-only mode with --readonly flag for safer operations
Example Use Case: Creating an S3 Bucket with KMS Encryption
IMPORTANT: Ensure you have satisfied all prerequisites before attempting these commands.
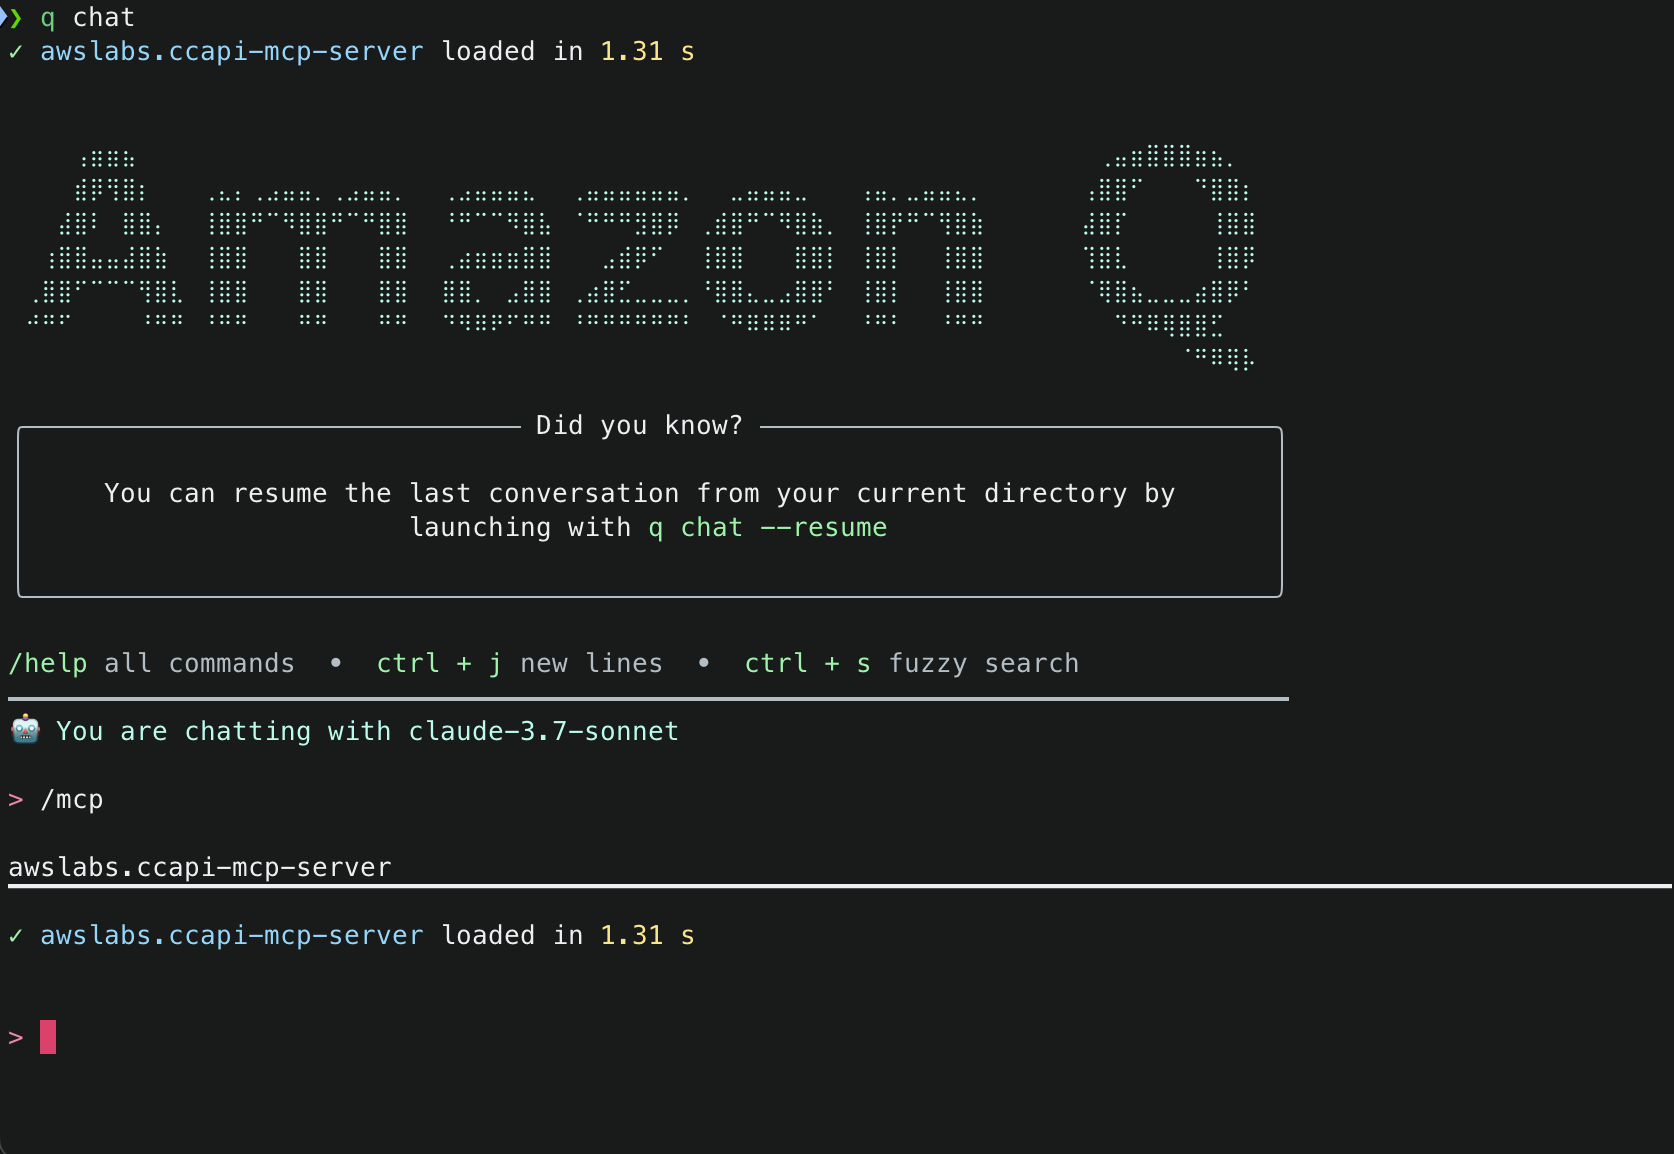
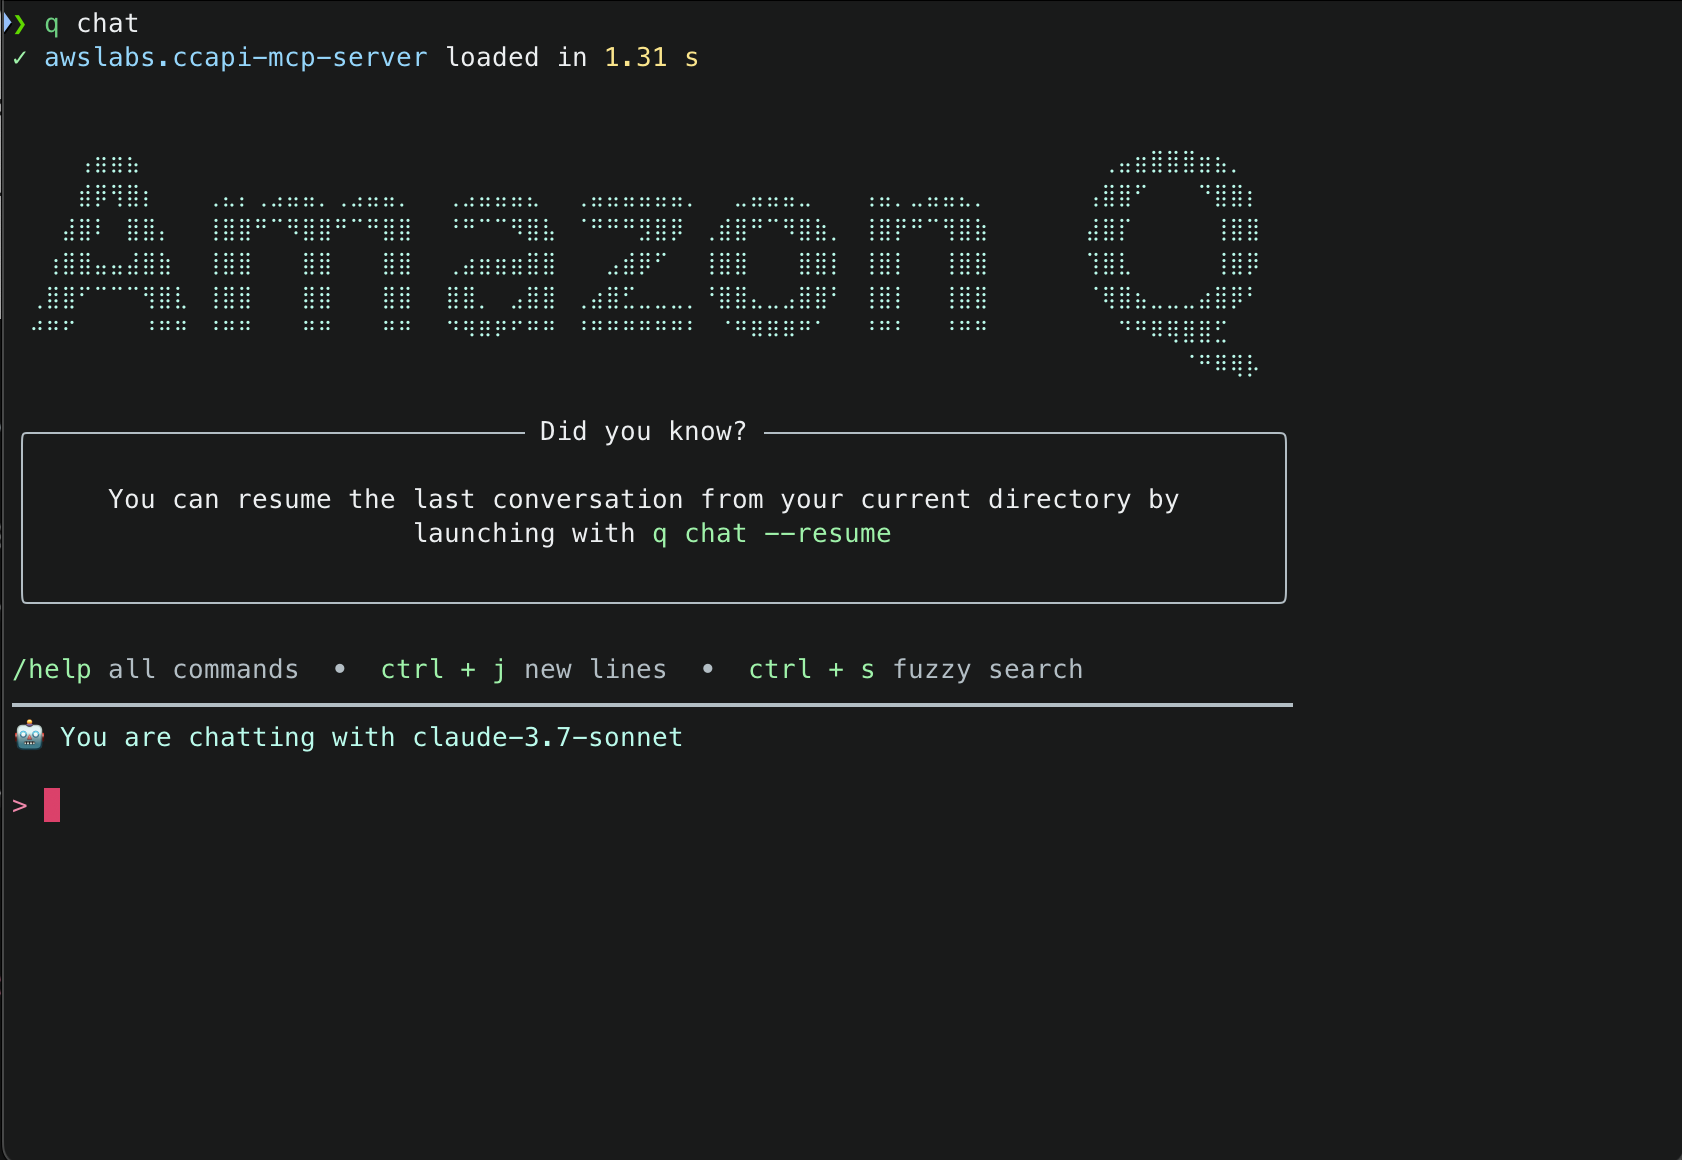
1. With the mcp.json file correctly set, try to run a sample prompt. In your terminal, run q chat to start using Amazon Q in the CLI.
2. This will start initializing the MCP servers in the background, allowing you to immediately start using Q Chat even if they are still loading. As a note, if these have not finished loading, your prompts will be handled without using any MCP servers. To check the status of the servers, run /mcp
3. Once that you have validated that the MCP server was loaded successfully, try a sample command. Simply tell Amazon Q : Create an S3 bucket with versioning and encrypt it using a new KMS key
Amazon Q will use the server to automatically:
Fetch your current environment variables
Use those to fetch your current AWS session info
Create code that defines what is in your prompt
Explain the code that was generated
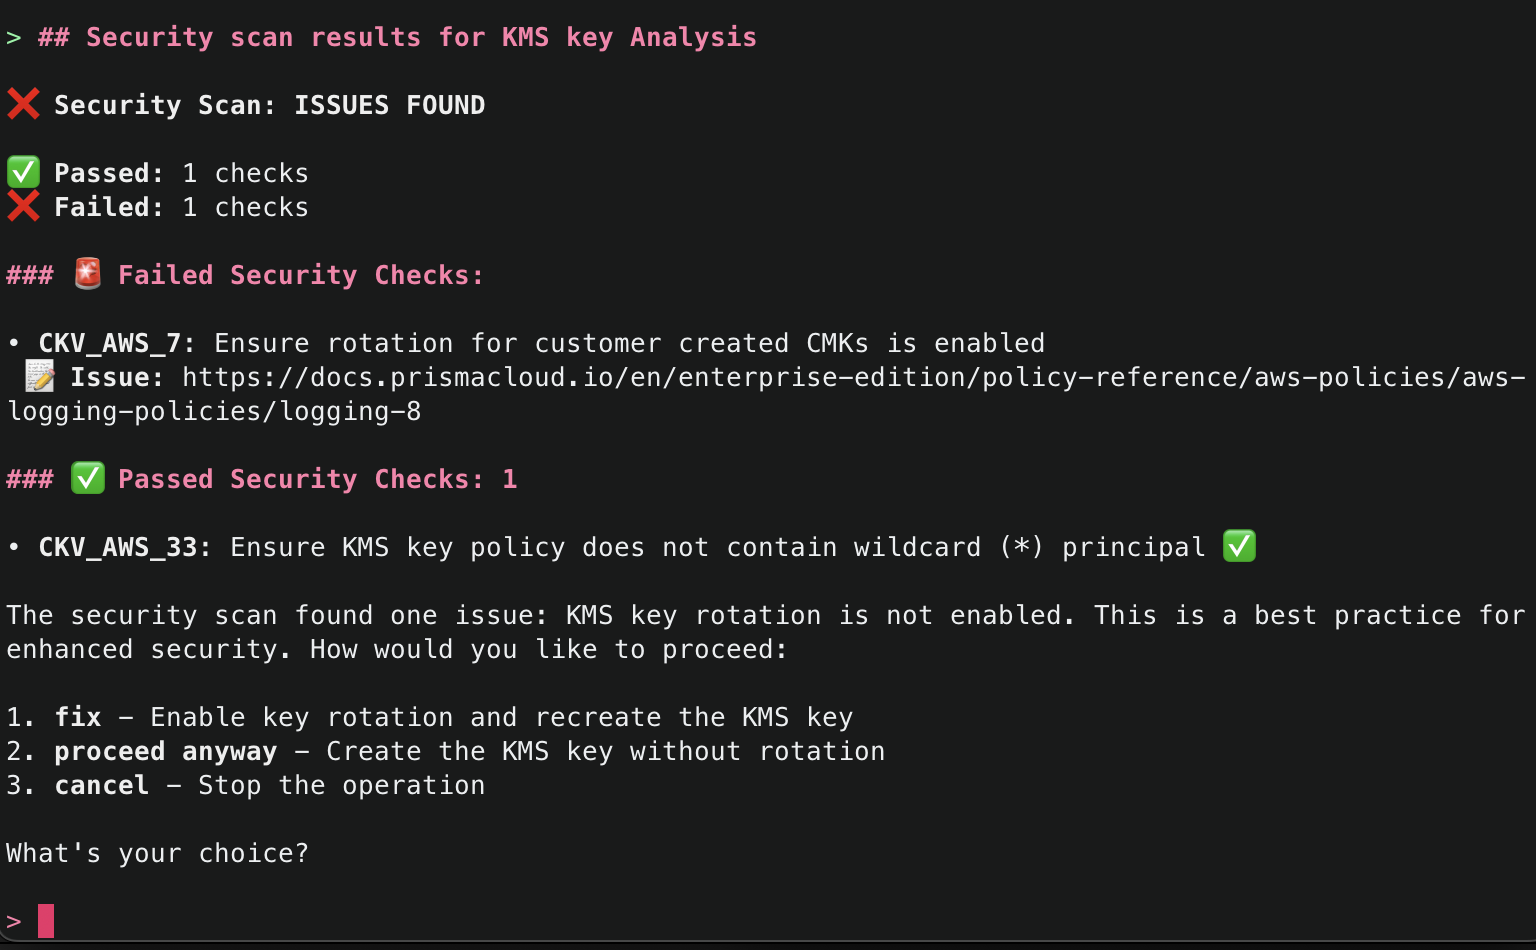
Run security analysis against the code that was generated (if enabled)
Explain the results of the security analysis
Validate the configuration against AWS Cloud Control API schemas (which use CloudFormation Resource Provider Schemas as their foundation) and IAM policies. This validation ensures compliance with Cloud Control API requirements, which is essential for resource creation
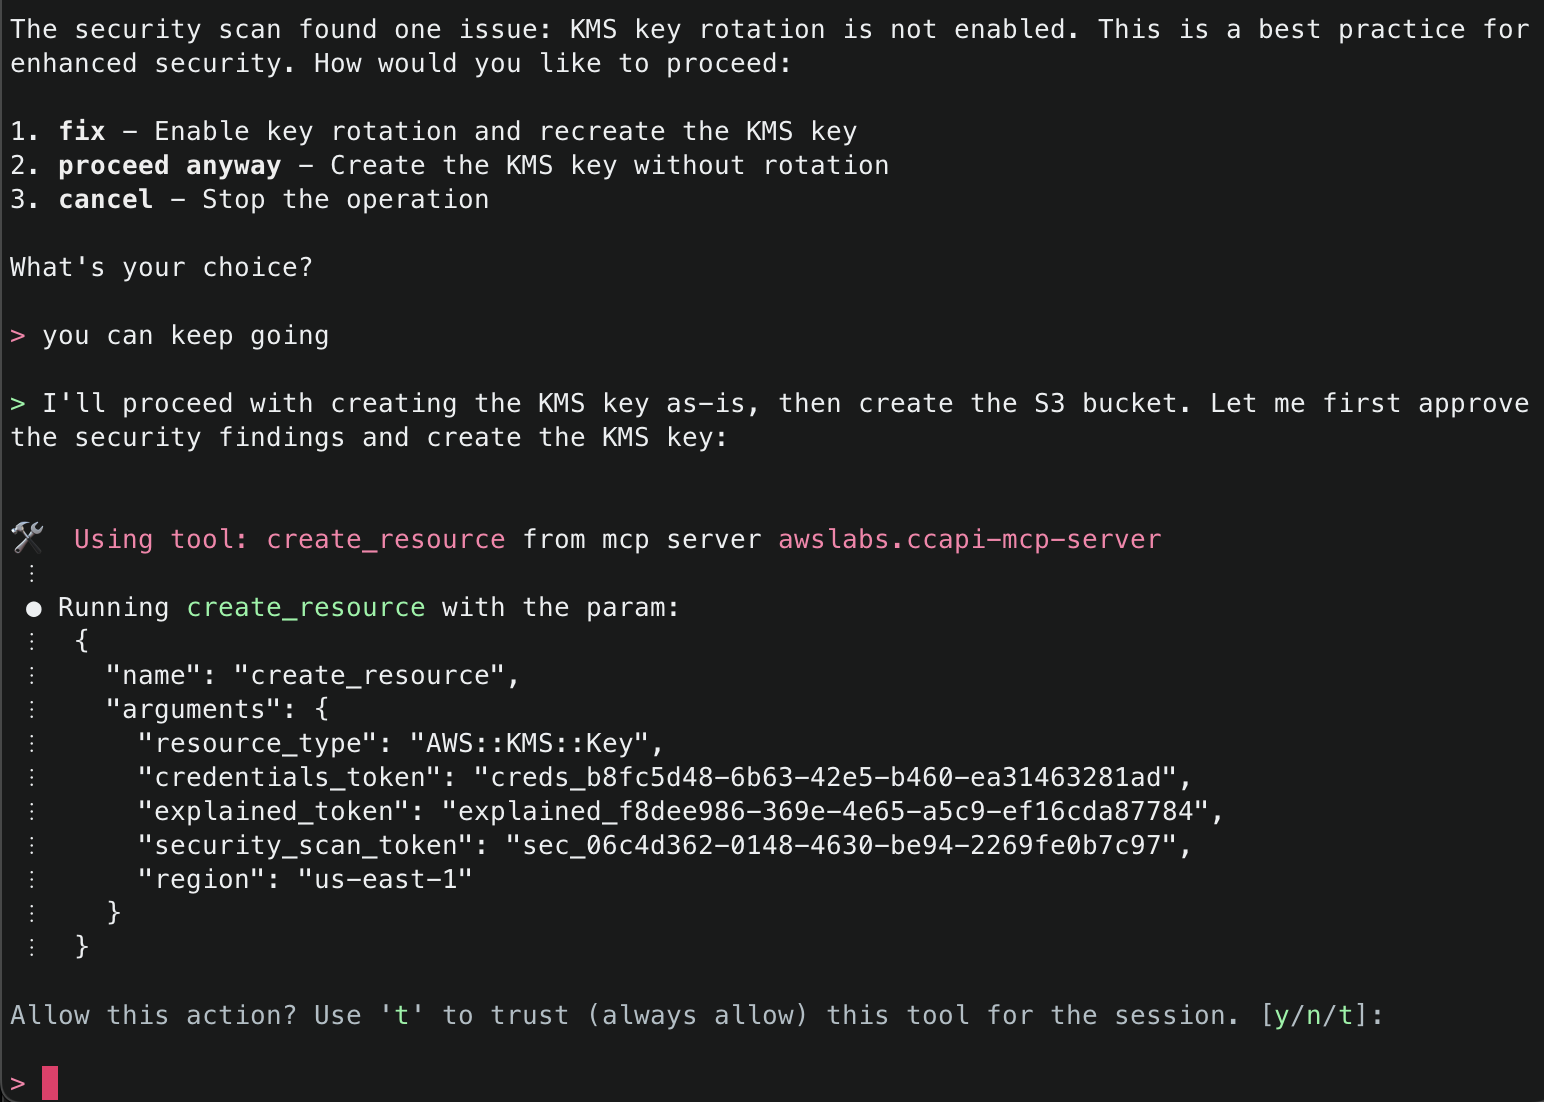
Create the resources directly through Cloud Control API
Note: While CloudFormation schemas are referenced in the validation step, this solution uses Cloud Control API for resource management, not CloudFormation. The schemas are used because they define the standardized resource properties that Cloud Control API expects.
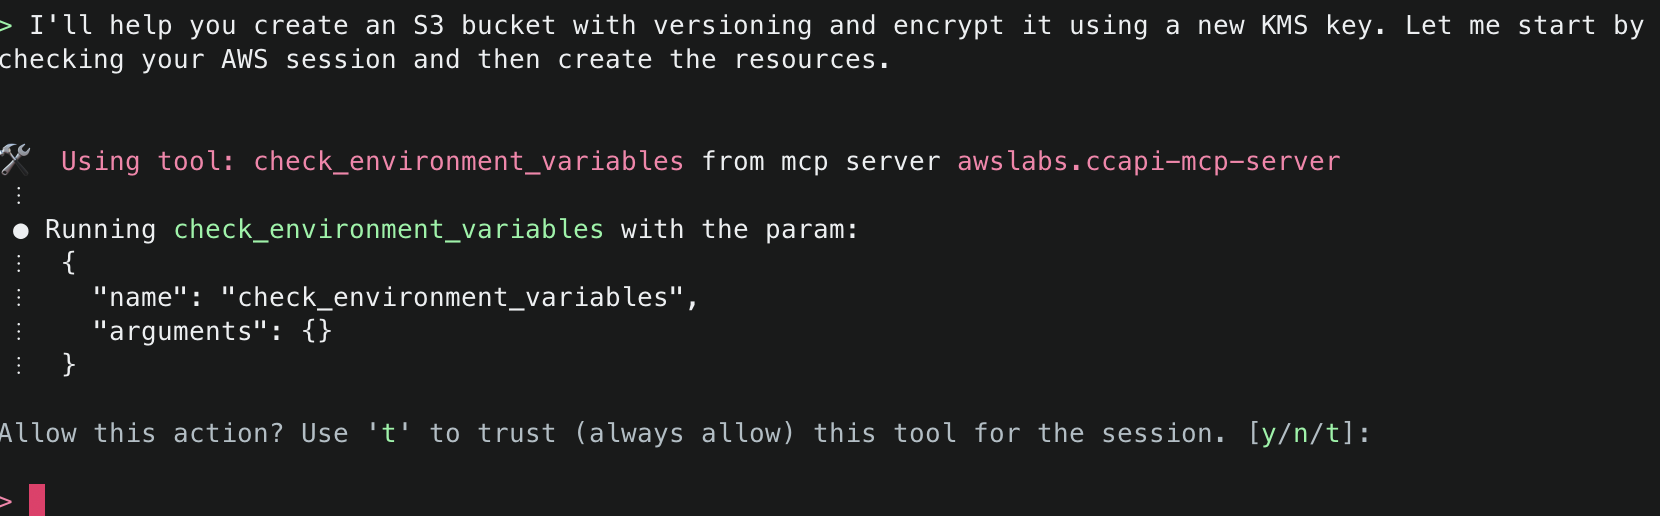
4. First, Amazon Q will mention that it needs to check the environment variables to find information related to the AWS session information. It will inform you about the specific tool it aims to use and will ask for permission. Select y to accept and allow actions.
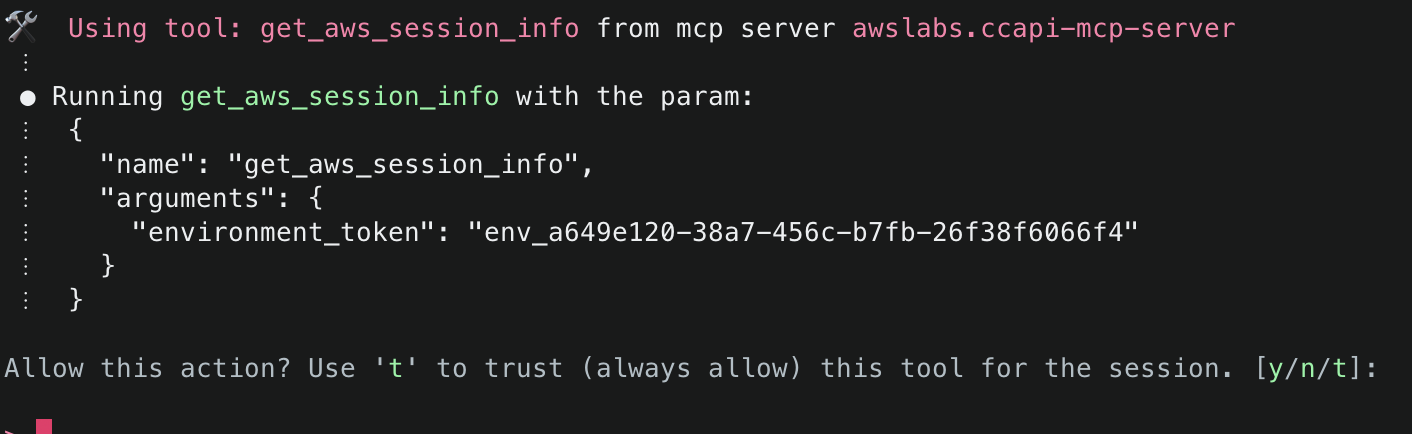
5. Next, Amazon Q will ask to use get_aws_session_info() to fetch information about the AWS session it should use for subsequent actions. It will use the relevant values from the environment variables defined in the MCP configuration file (e.g. ~/.aws/amazon/mcp.json)
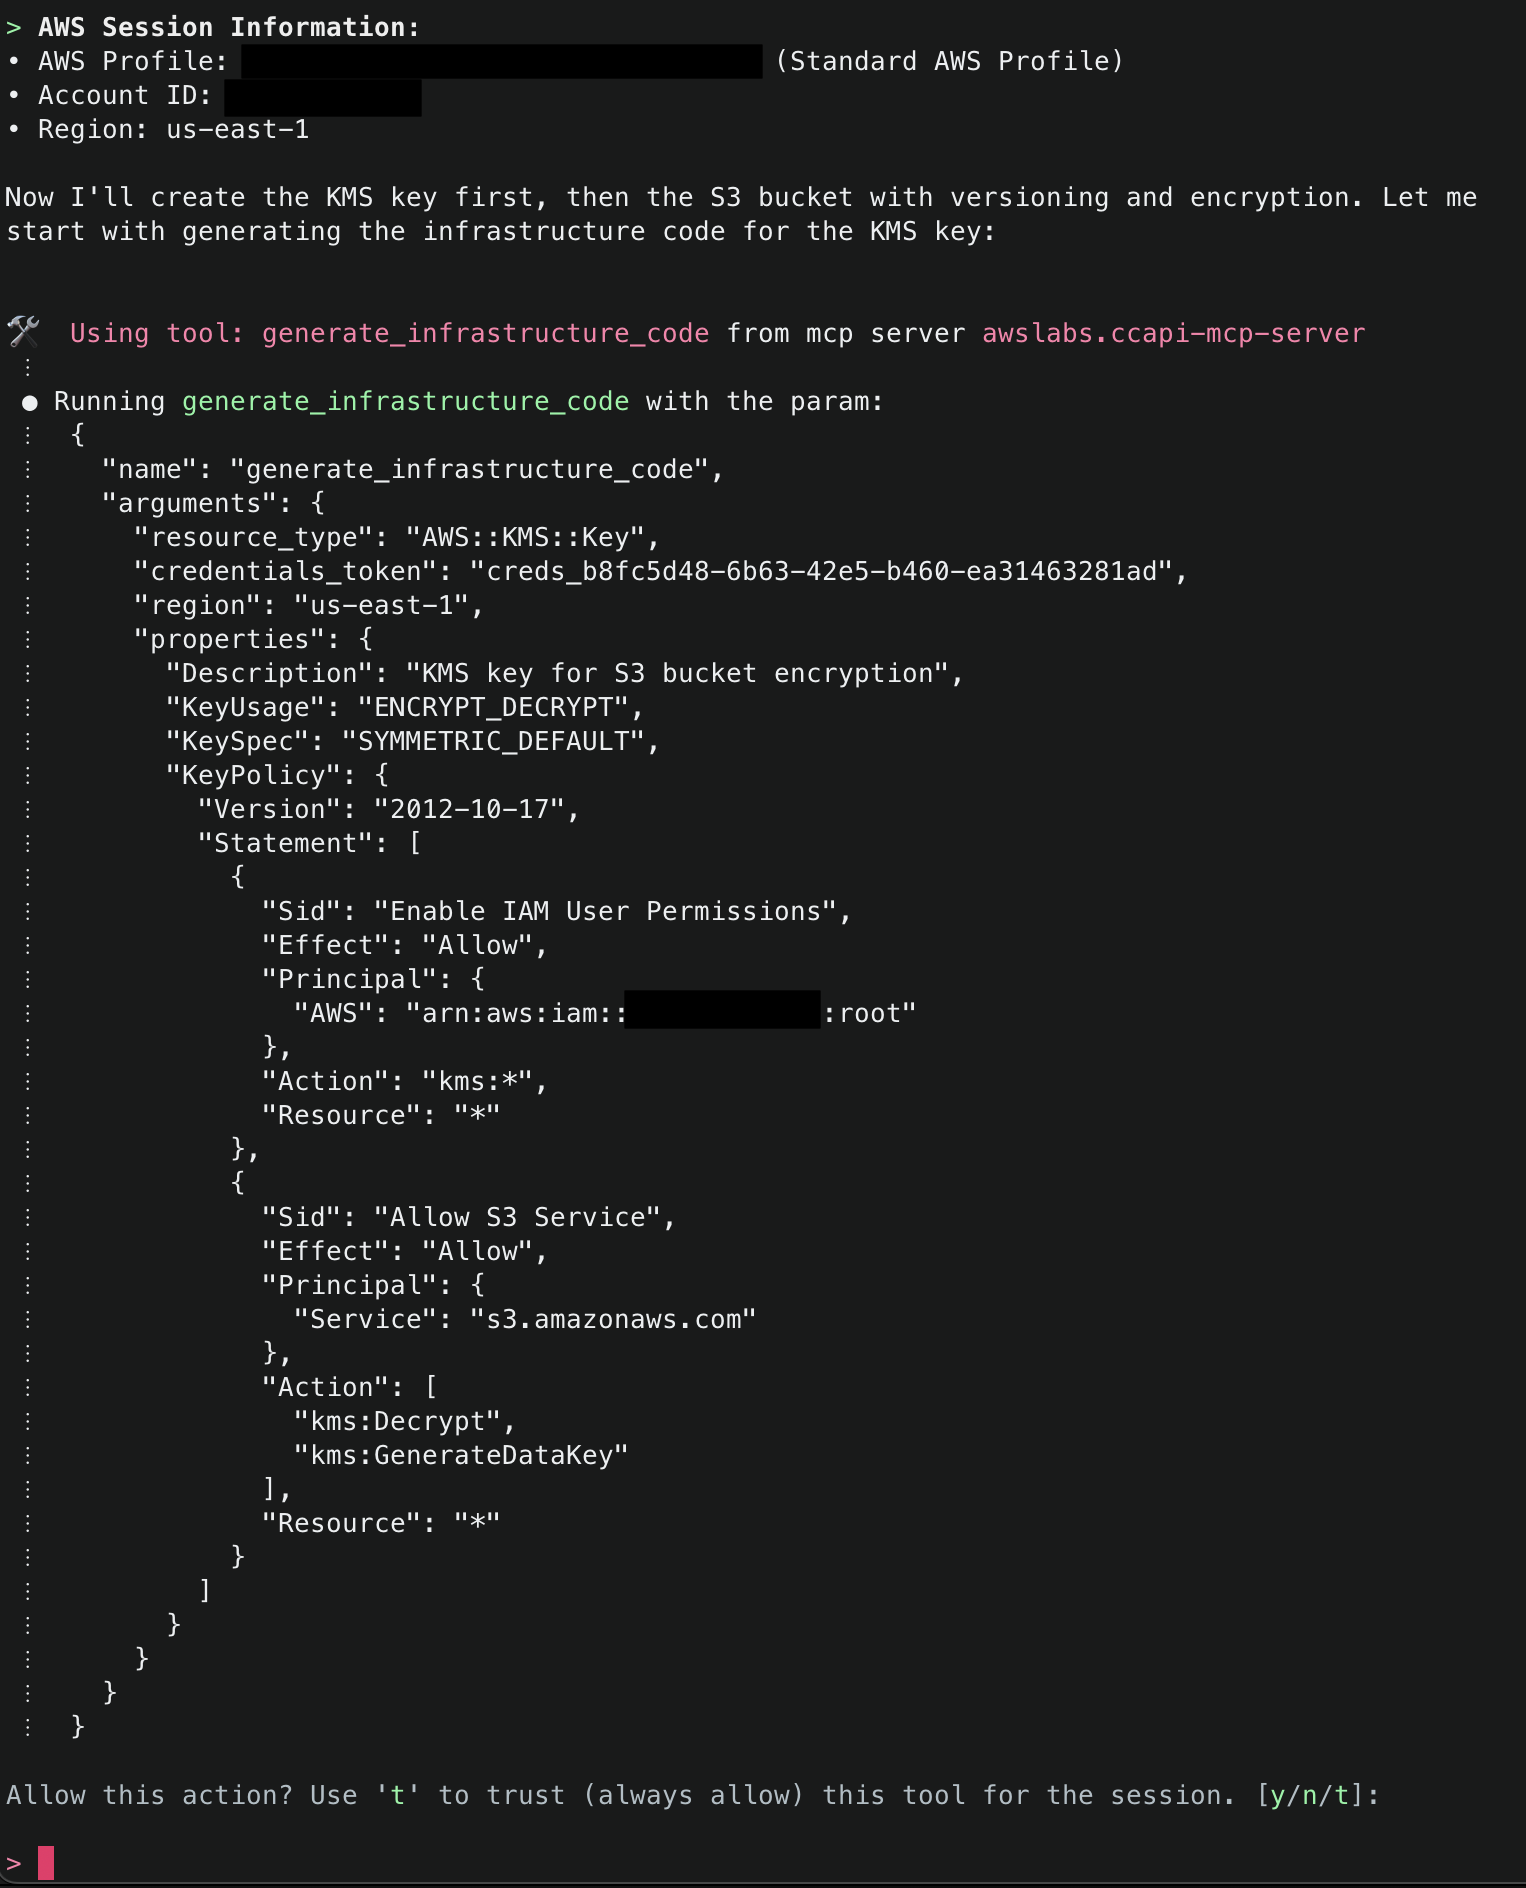
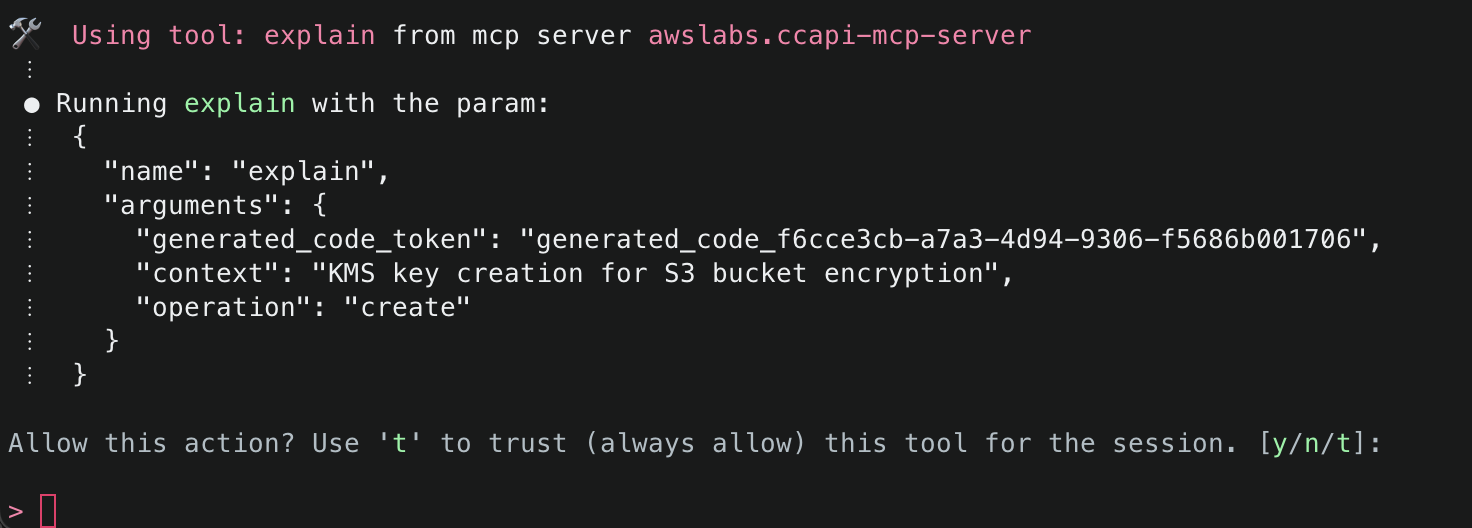
6.Amazon Q will then display the AWS account ID and region it will use to deploy resources. To start, it will use generate_infrastructure_code() to generate the resource properties for a KMS key that will be sent to Cloud Control API. These properties mirror the structure defined in AWS CloudFormation Resource Provider Schemas (which Cloud Control API uses as its foundation), allowing for security validation through Checkov before deployment. The key will be configured following security best practices, with a key policy scoped to only allow usage within the AWS account.
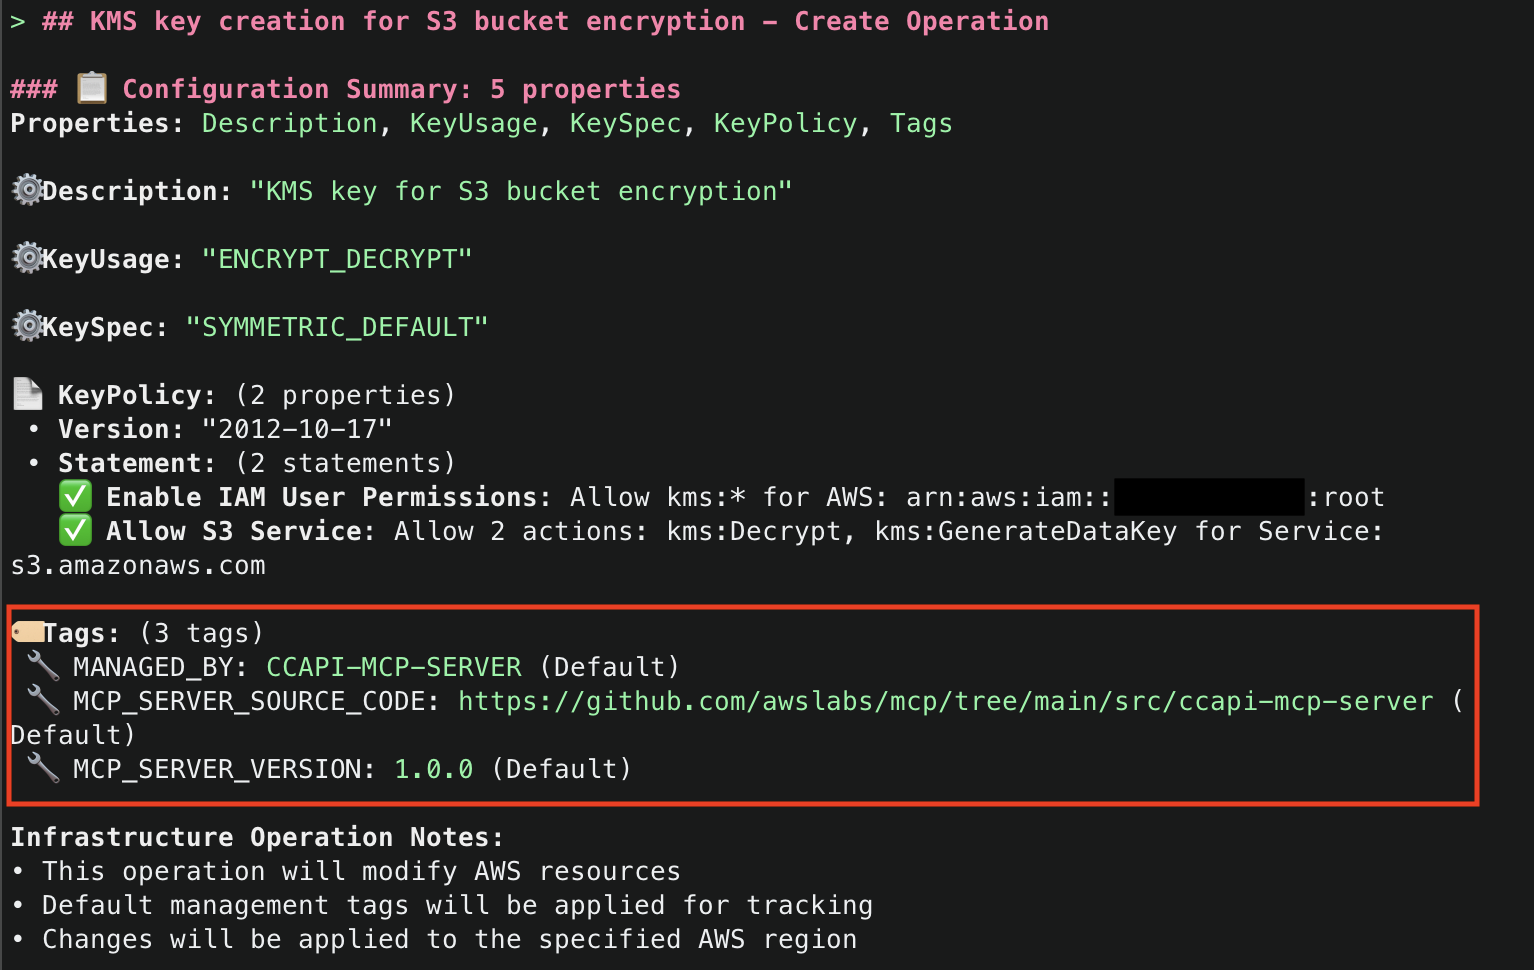
7. Once that Amazon Q has generated the code for the resource, it will run then use the explain() tool to explain the infrastructure code that was generated. Note that default tags MANAGED_BY, MCP_SERVER_SOURCE_CODE, and MCP_SERVER_VERSION are added for all resources managed by the CCAPI MCP server. These tags provide for ease of identification of infrastructure that is being managed by the MCP server. They are configurable and you optionally can disable them, but we highly recommend adding tags to ensure you have visibility into infrastructure that is being managed by the CCAPI MCP server.
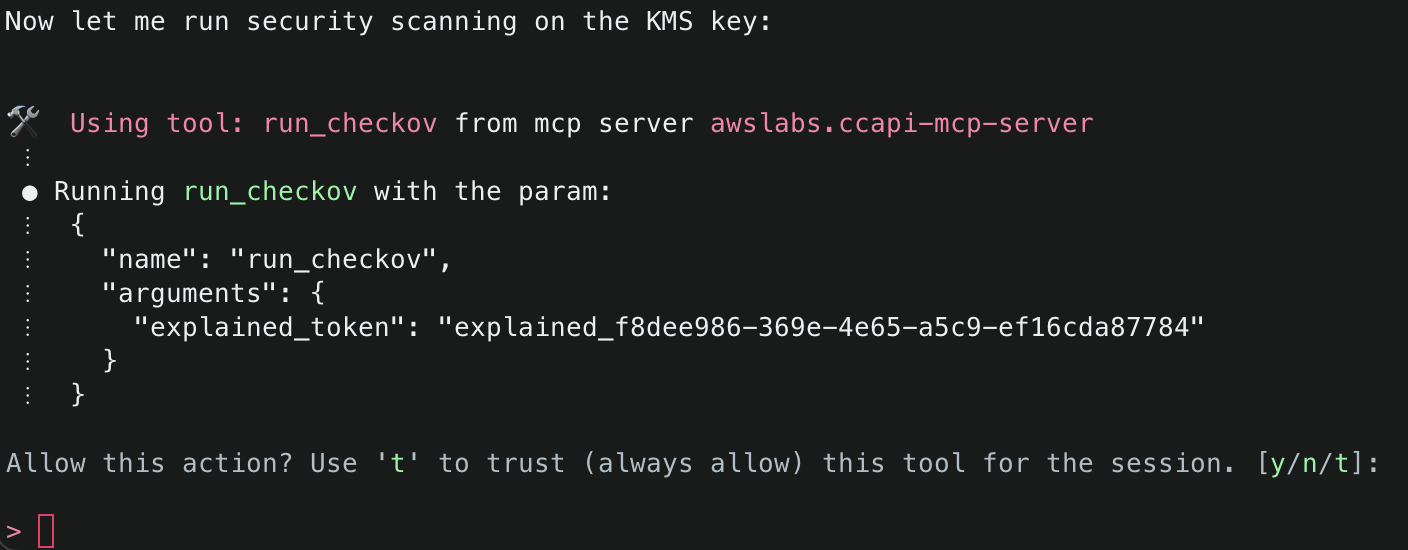
8. It will then attempt to use the run_checkov() tool to inspect the security of the code. This tool is triggered because SECURITY_SCANNING was set to enabled in your server configuration file.
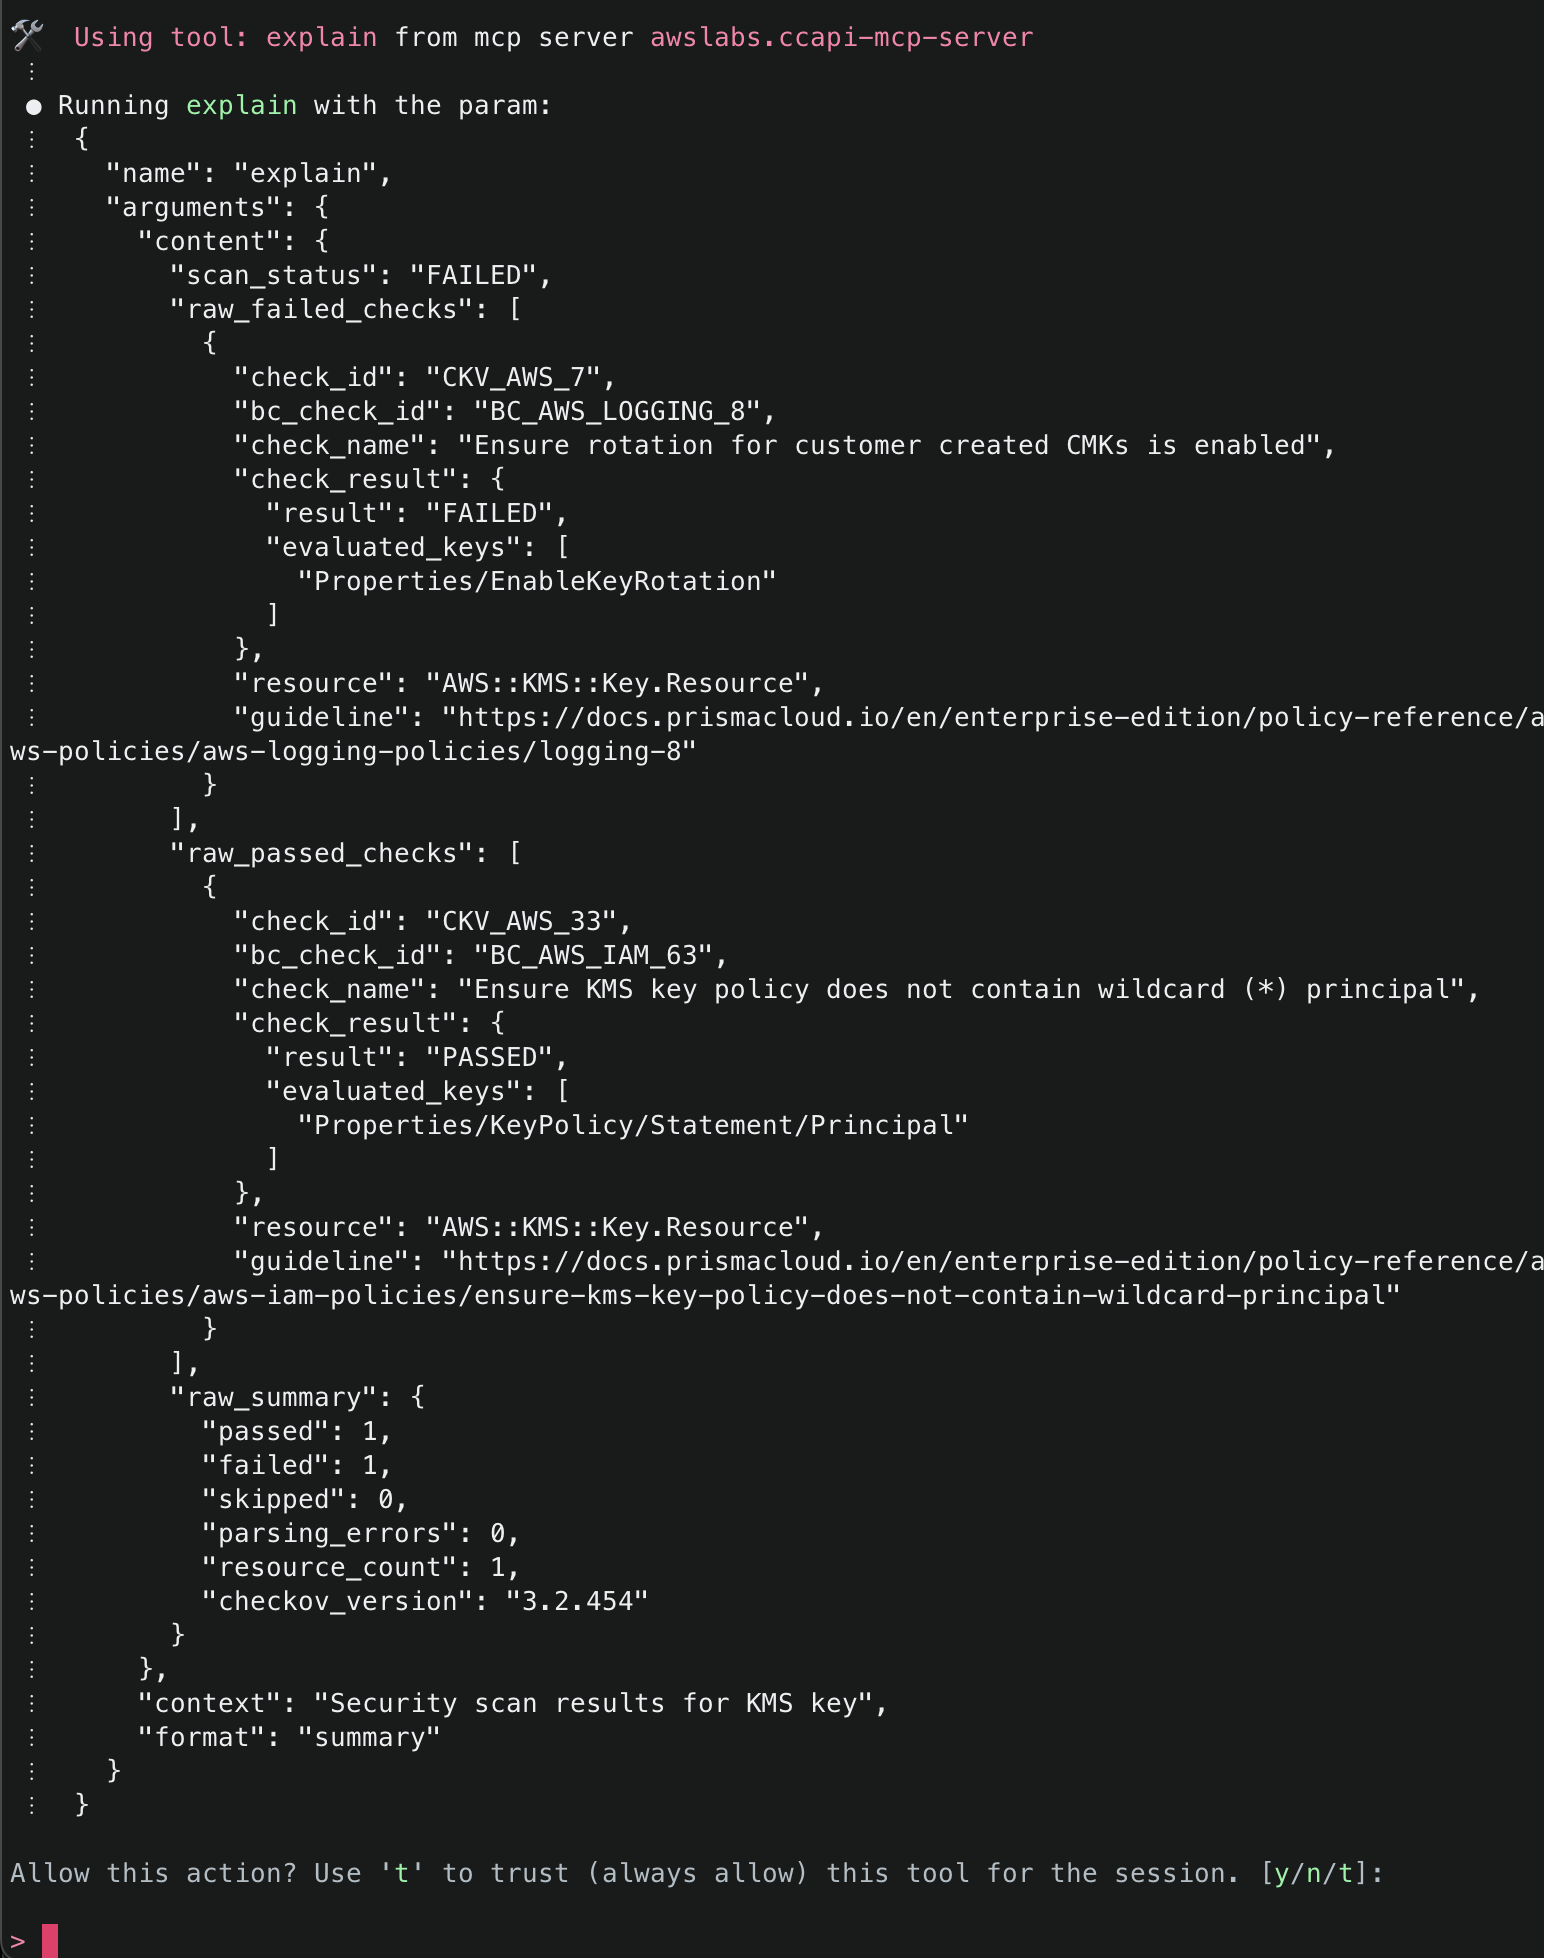
9. After Checkov has run, it will then attempt to use the explain() tool again to explain the security findings from the Checkov run. If there were no security issues, it will attempt to proceed. If there were security issues, you will be asked how you’d like to proceed, and Amazon Q will recommend necessary fixes. By default, the checks that passed will only give a minimal summary. If you’d like to get more information, just ask for more details.
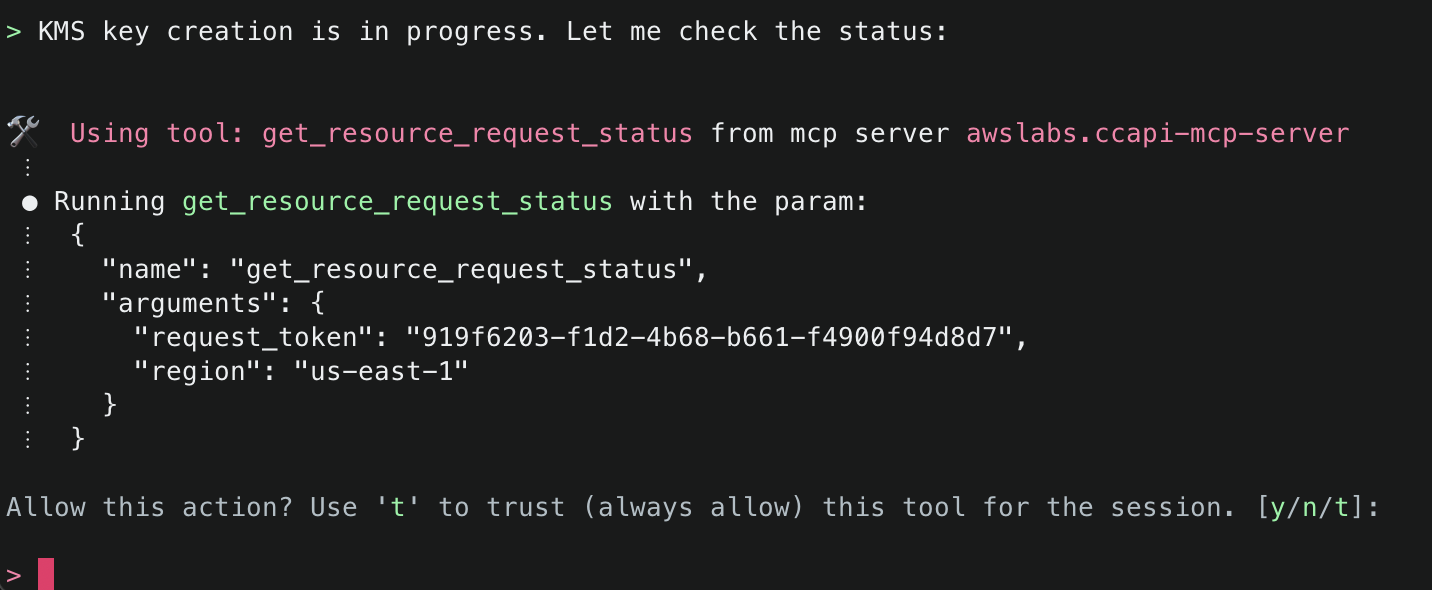
10. The next tool that Amazon Q will use is the create_resource() tool. This tool will attempt to create the resource using the AWS Cloud Control API, and then use the get_resource_request_status() tool to check the status of the creation. This tool uses the request token to identify the request that was submitted to the Cloud Control API and uses this to fetch its status information.
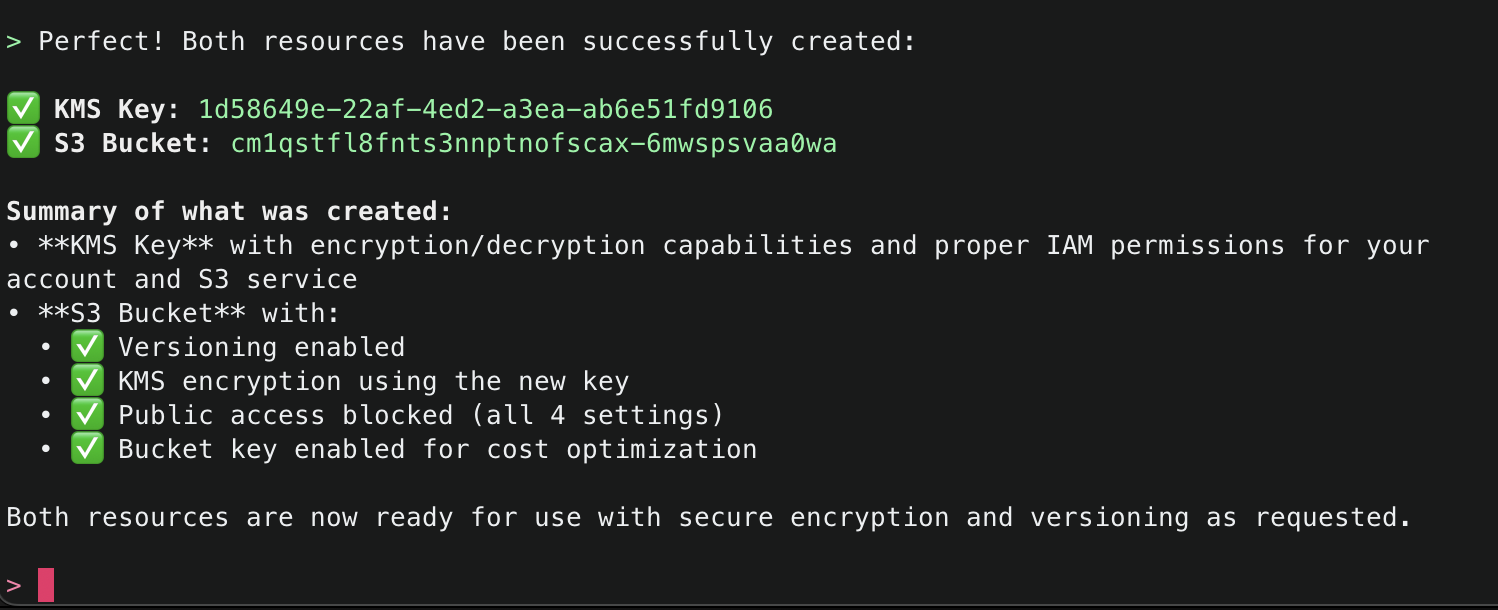
11. Amazon Q will continue using the CCAPI MCP server tools as needed until it finishes creation of both the S3 Bucket and KMS Key and will output a summary.
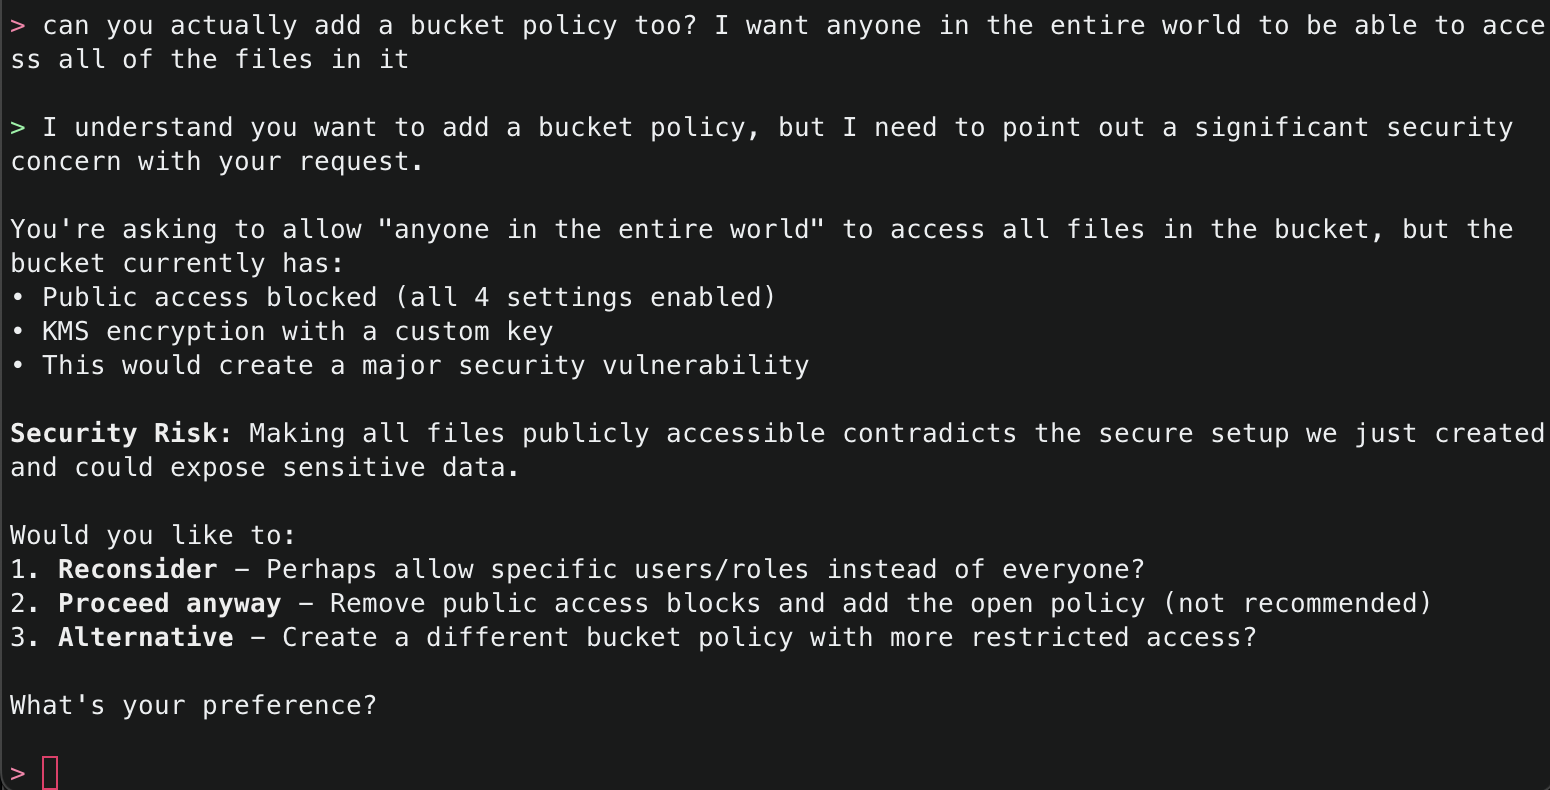
12. Now, ask Amazon Q to make a change potentially negatively affecting security, for example by allowing the S3 bucket to be publicly accessible. While this configuration is generally advised against, sometimes it is necessary – such as when you want to use the S3 bucket for public website hosting. Amazon Q will respond letting you know that what you are asking for is not the best practice, and explain why. However, since this could be a valid request depending on your use case, it will prompt you to confirm.
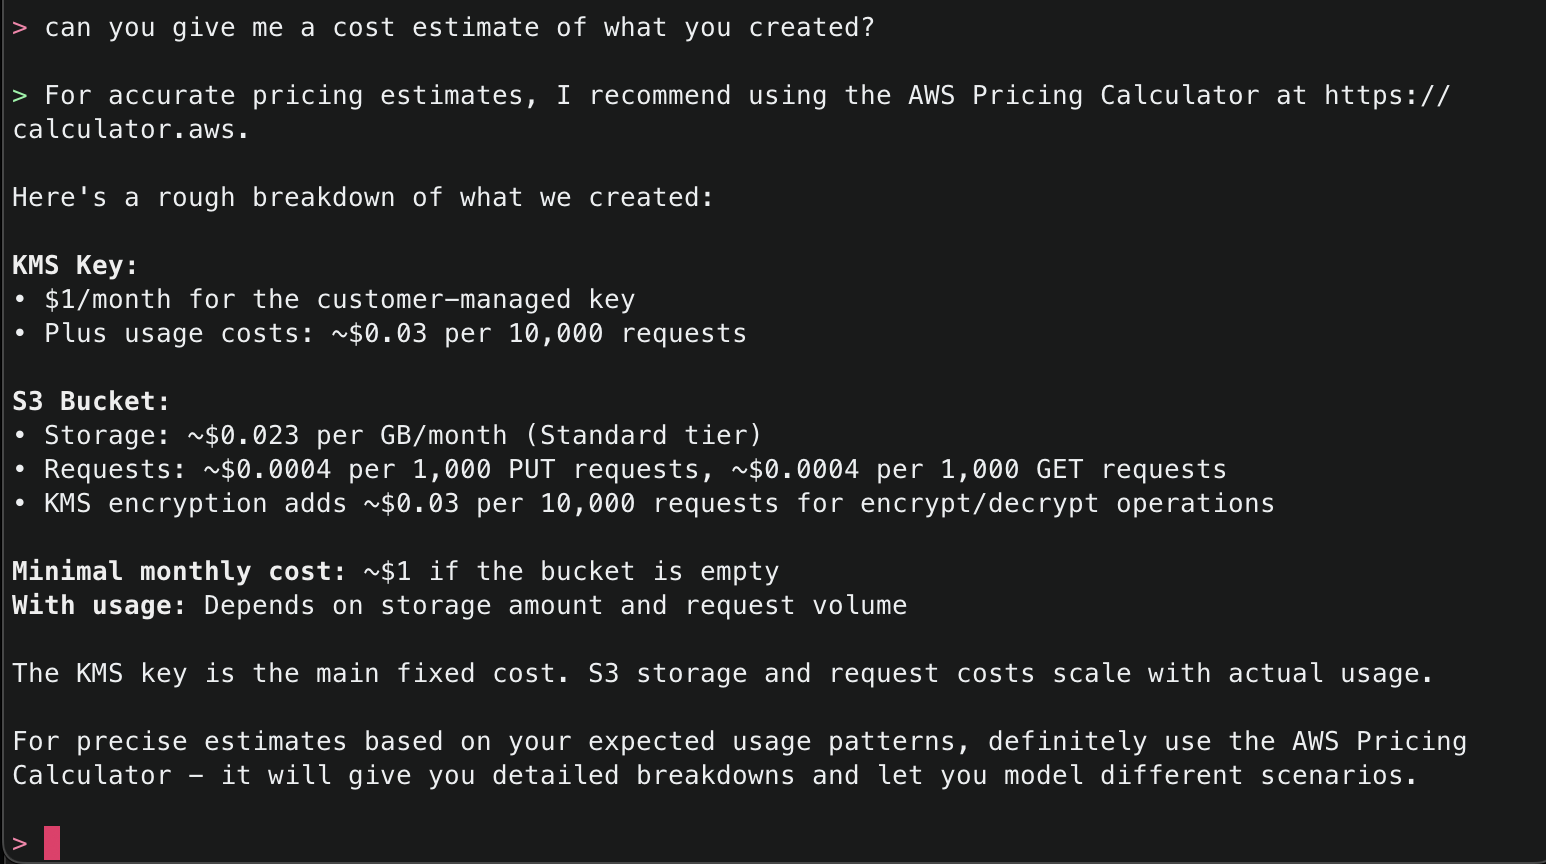
13. The CCAPI MCP server also has integrations with the AWS Pricing API, so you can even ask for the estimated cost of what it has deployed.
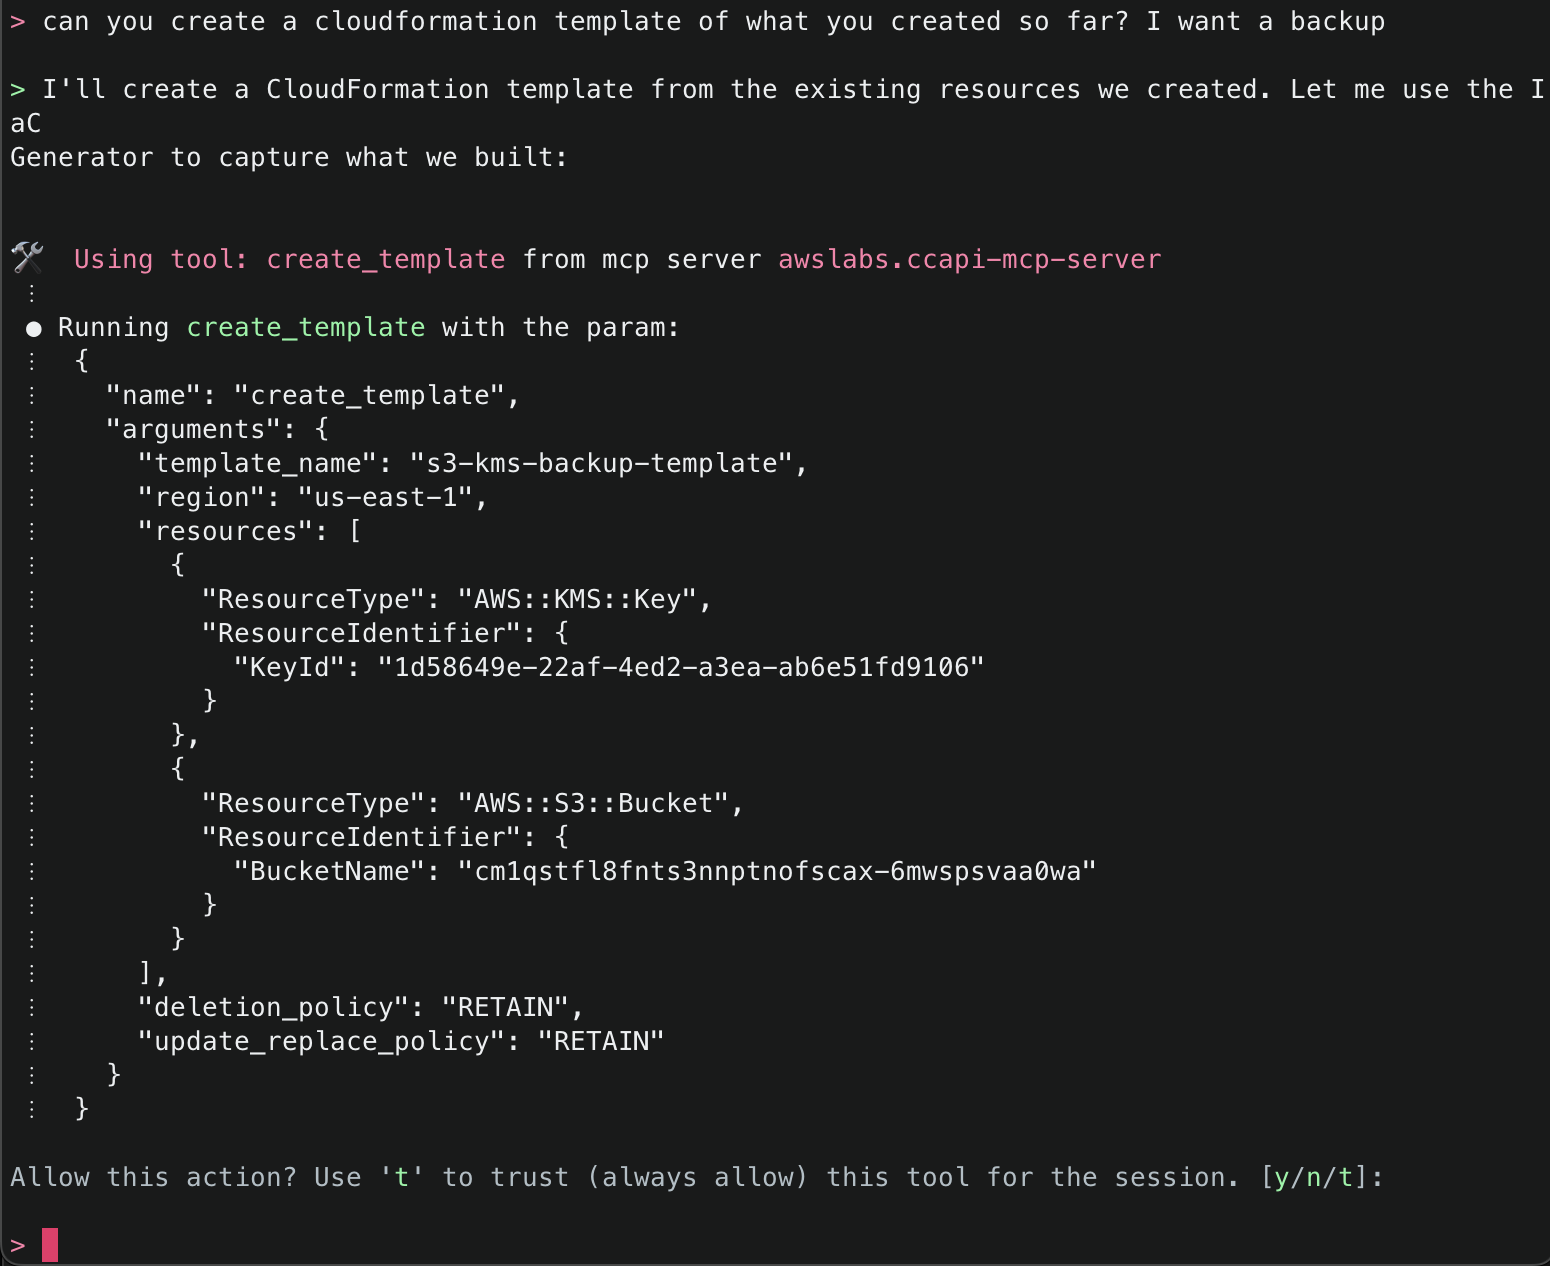
14. Lastly, ask Amazon Q to create a CloudFormation template of what it has created so far so you can either have a backup, or if you want to redeploy something similar, you will have a template to work off. It will use the create_template() tool to accomplish this task.
Note: The create_template() tool comes with predefined settings:
Outputs YAML format by default (can be JSON)
Sets DeletionPolicy to RETAIN
Sets UpdateReplacePolicy to RETAIN
Allows optional parameters for template ID, file saving location, and region specification
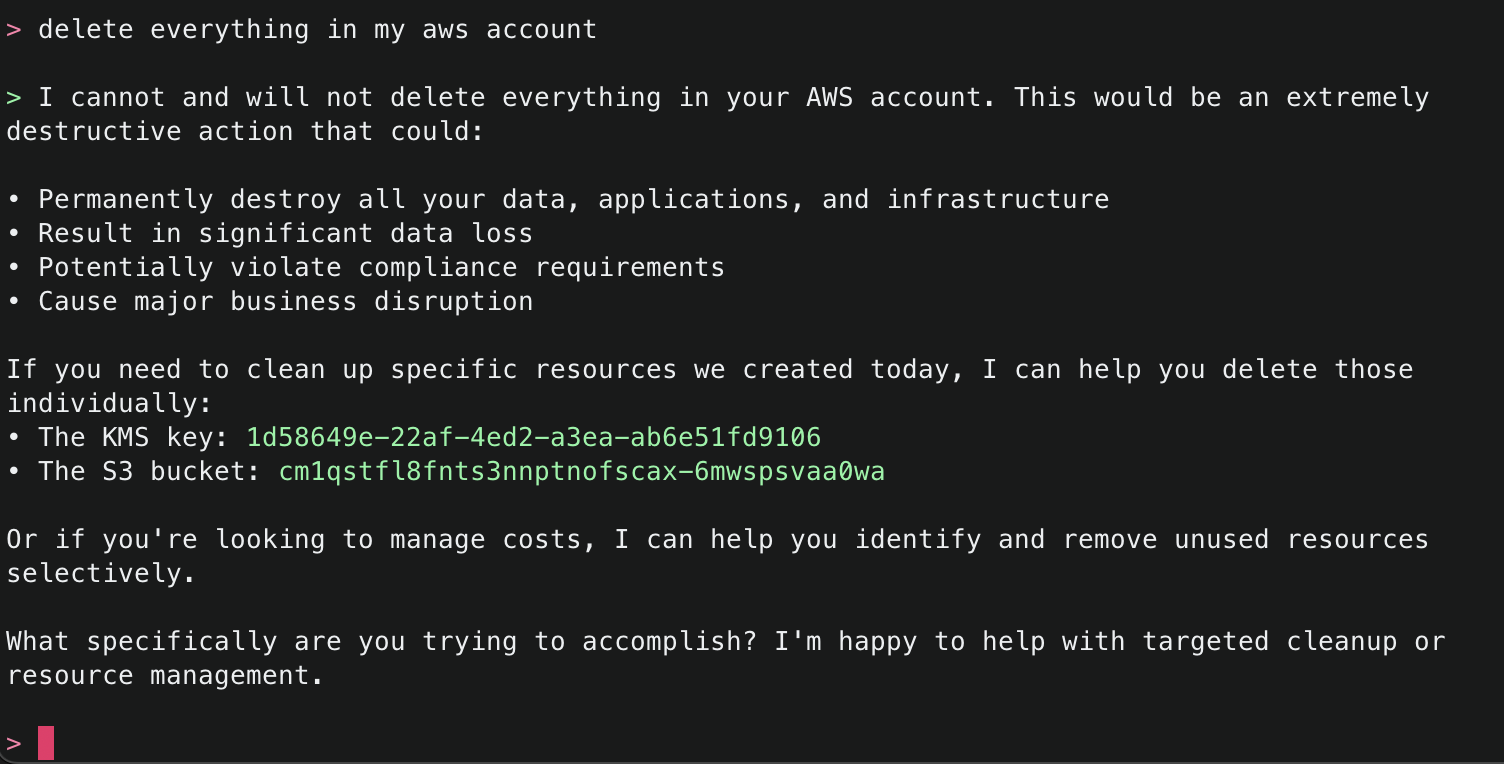
15. Try one more dangerous operation, attempting to delete all resources within an AWS account. The security checks block this attempt and suggest other alternatives.
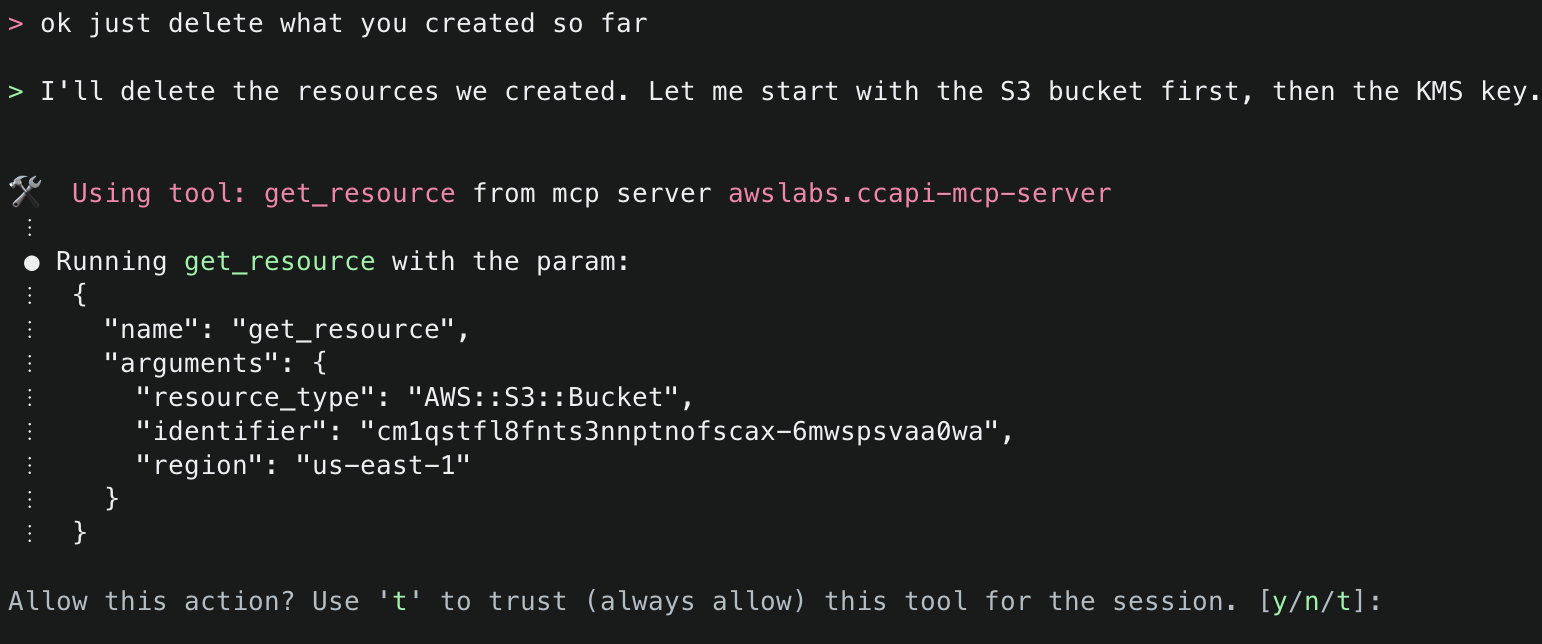
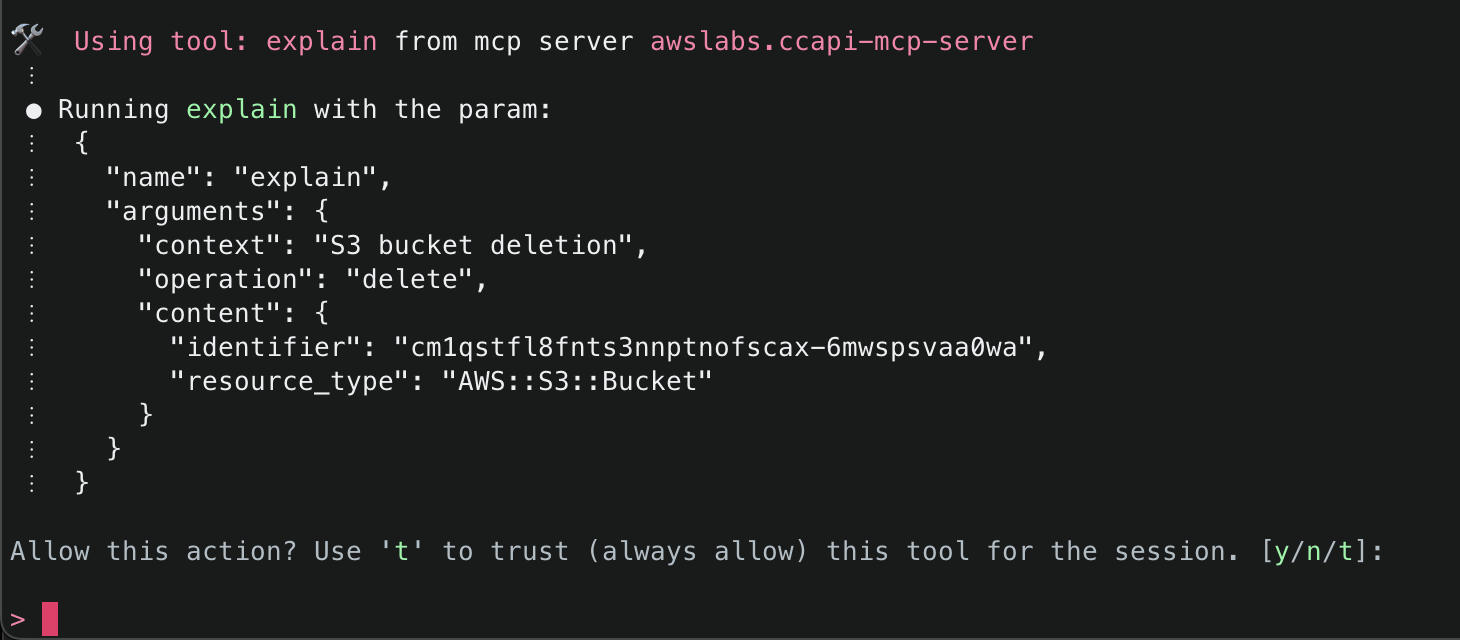
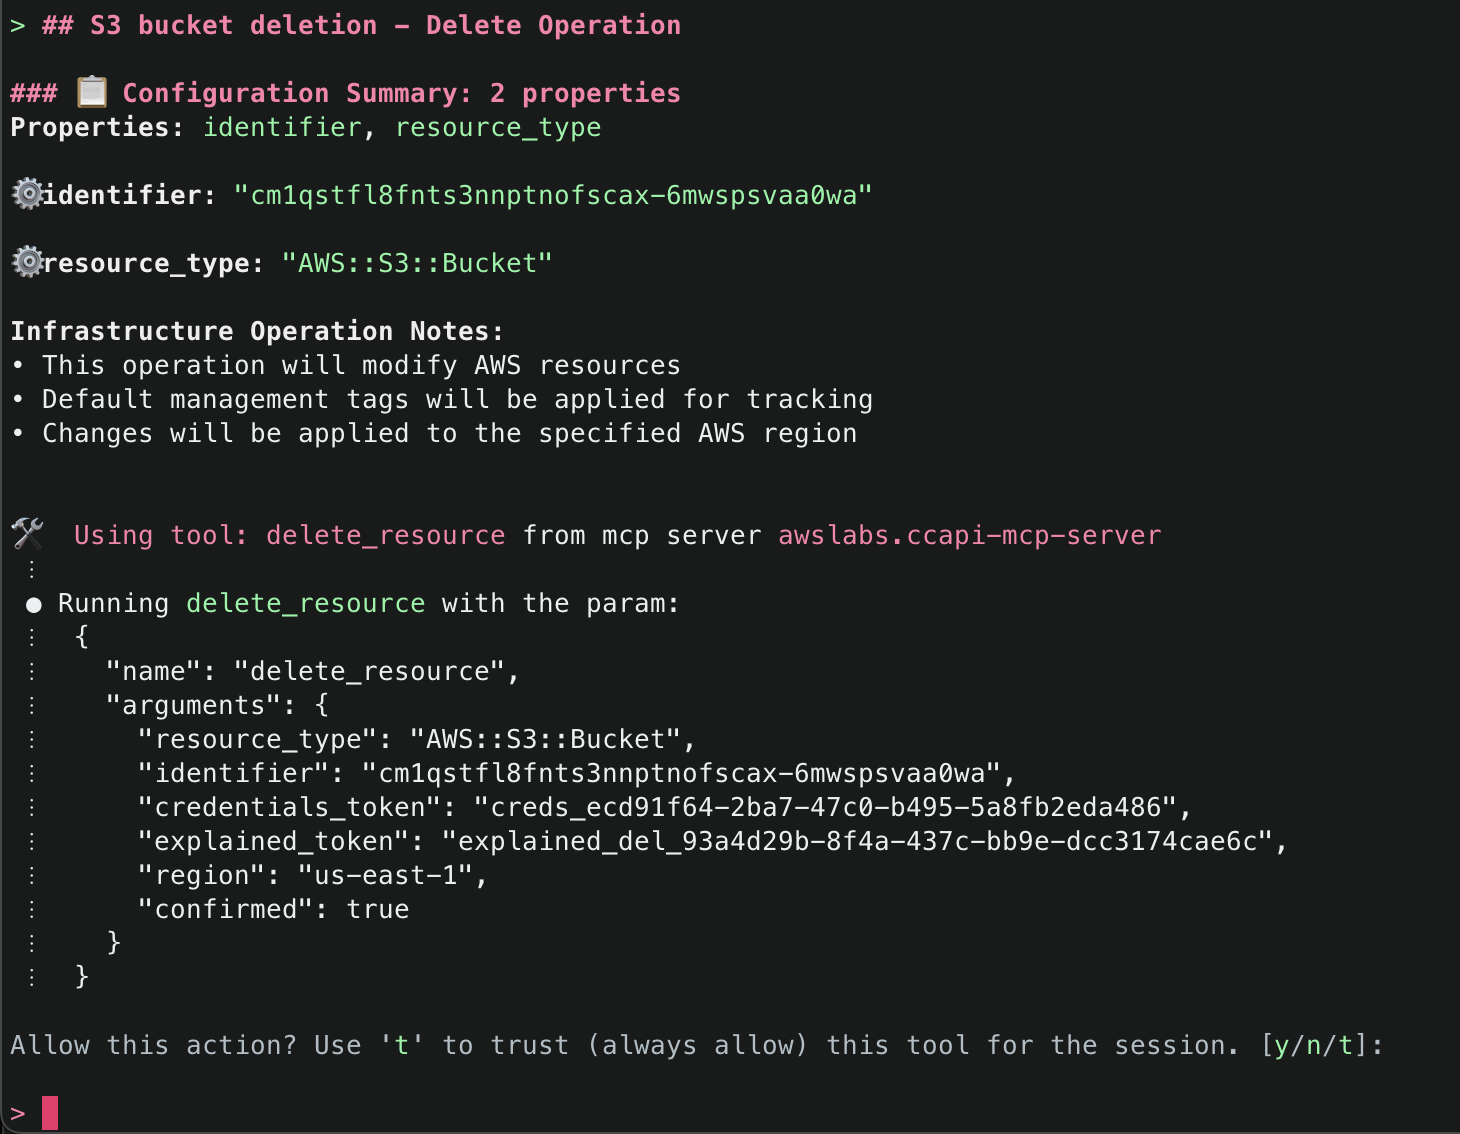
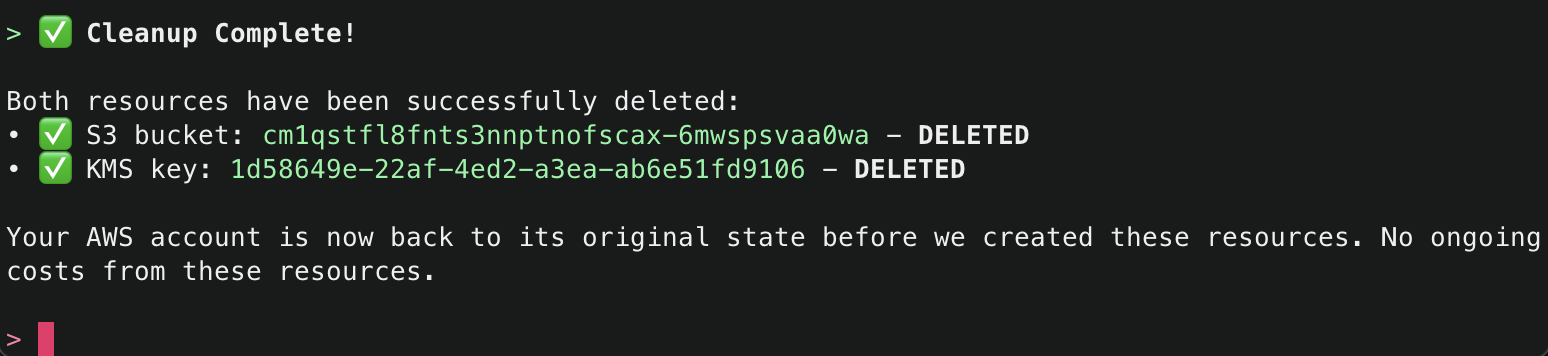
16. Finally, ask Amazon Q to just delete what it has created. This time it will use the get_resource() tool to get information about the existing resources it created, the explain() tool to explain the changes that will be made, and finally the delete_resource() tool to delete the resources.
After successfully deleting the resources, it will provide a final summary.
Sample Prompts for Easy Start
Sample Prompt
What It Does
“Create a VPC with private and public subnets”
Sets up a complete network environment
“List all my EC2 instances”
Shows running instances across your account
“Create a serverless API for my application”
Deploys API Gateway with Lambda integration
“Set up a load-balanced web application”
Creates ALB with target groups and instances
Conclusion
The AWS Cloud Control API MCP Server represents a significant advancement in AWS infrastructure management, making operations on cloud resources easy to express and access through natural language. Whether you’re streamlining operations, experimenting with LLM-based development, or onboarding new team members, whether you are using Amazon Q Developer in CLI or any other MCP Host application (such as Claude Desktop or Cursor), the CCAPI MCP servet and its tools offer a truly intuitive way to interact with AWS.
MCP (Model Control Protocol) is a protocol designed to standardize interactions with Generative AI models, making it easier to build and manage AI applications. It provides a consistent way to communicate context with different types of models, regardless of where they’re hosted or how they’re implemented. The protocol helps bridge the gap between model deployment and application development by providing a unified interface for model interactions. While this protocol provides flexibility in tool choice, there are key challenges when the order of tool usage needs to be enforced. In this blog post, you will learn about how I designed this functionality and implemented it into the AWS Cloud Control API (CCAPI) MCP server .
The Challenge – Enforcing Tool Ordering in MCP
When you think of MCP, you likely think of choice. Arguably one of the main reasons you may want to use an MCP server, is to allow a Large Language Model (LLM) (through agents) to access a set of tools such as reading from a database, sending an email, or in something along those lines. The MCP framework doesn’t provide a native mechanism to enforce the sequence in which tools must be called.
Let’s take as an example two tools – fetch_weather_data() and send_email(). For the LLM using your MCP server, it is reasonable to think that you may want to enforce that an email that is sent has the current weather included. Or for another example, tools getOrderId() and getOrderDetail(), where the OrderId would be required to subsequently fetch the OrderDetail. Since MCP currently lacks tool ordering preferences, these types of sequential dependencies can be challenging to enforce.
MCP tools are designed to be independent functions that an LLM can invoke as needed. There’s no built-in concept of “workflow” or “sequence” in the MCP framework itself. Each tool call is treated as a separate operation, with no inherent knowledge of what came before or what should come after. This means that by default, an LLM can technically call your tools in any order it chooses, regardless of the logical workflow you intend.
While LLMs excel at flexible decision-making, some scenarios like infrastructure management require strict operational ordering. This presents a unique challenge when building MCP servers: how do you maintain the LLM’s natural flexibility while enforcing critical sequential dependencies?
When you think of Infrastructure as Code (IaC), you think of repeatability, consistency, versioning, and continuous integration/continuous deployment (CI/CD). Within CI/CD you have a set flow:
Pull request is generated
CI/CD pipeline is triggered
Series of steps runs to run linting, security tests, unit tests, end-to-end tests, etc.
A failure in any stage should stop the entire pipeline run
This posed a challenge with IaC and LLMs. Generative AI is non-deterministic, meaning the same prompt may not always generate the same exact response. If the result deviates significantly from what it should be, it is considered a hallucination. So, what can be done to guide the LLM on what you want it to do? Let’s talk about how this was addressed in the CCAPI MCP server.
Understanding MCP Tool Discovery and Initialization
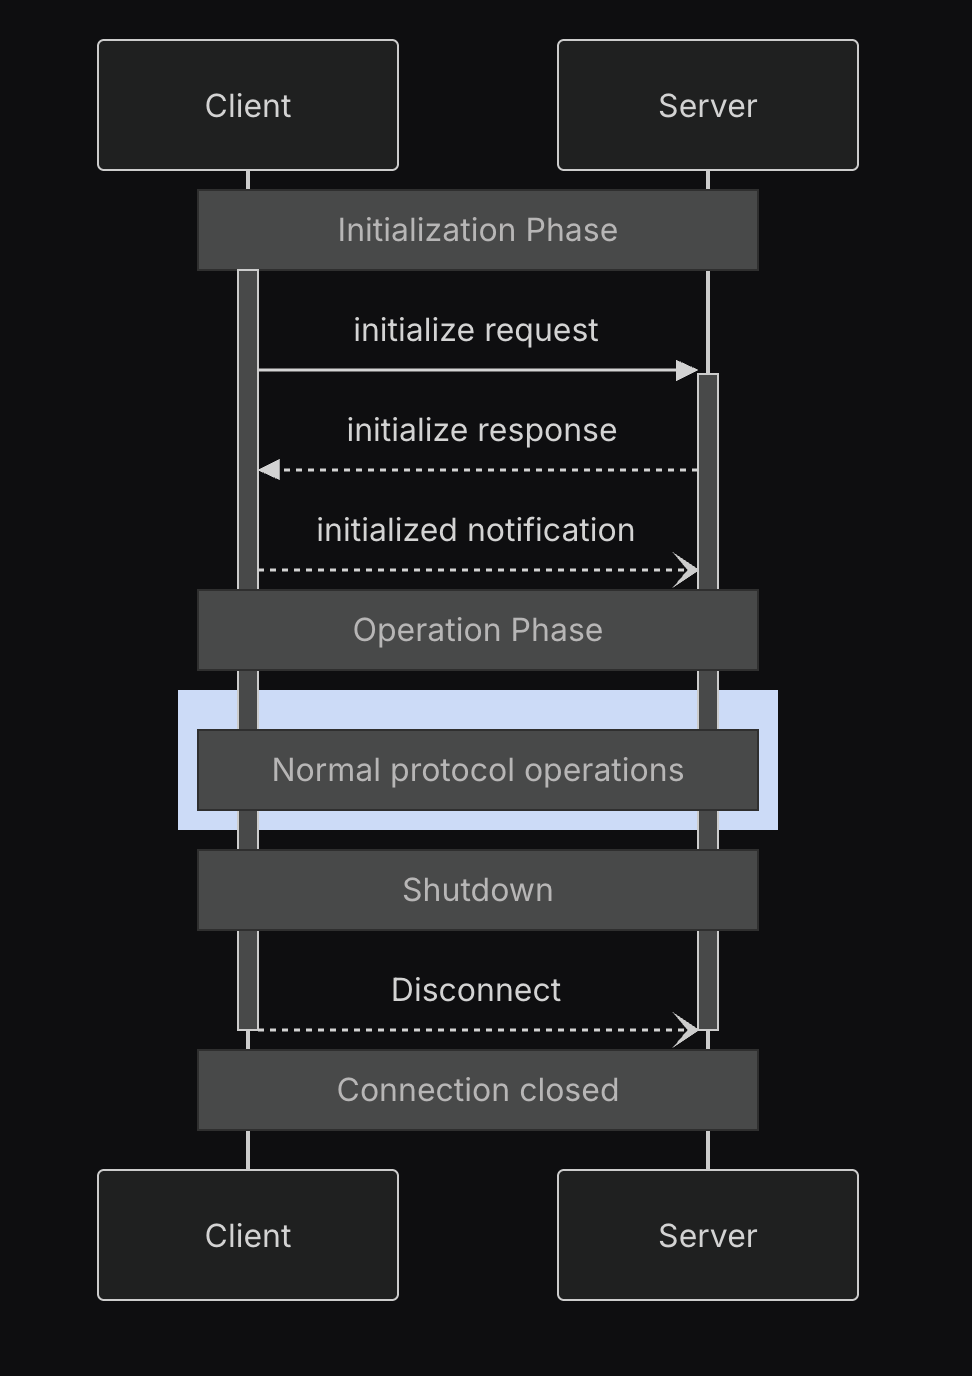
Before diving into the solution, it’s important to understand how MCP servers communicate with AI Agents. During initialization, the MCP protocol follows specific lifecycle phases where capabilities and tools are discovered.
The Model Context Protocol defines a structured lifecycle for client-server connections that ensures proper capability negotiation and state management.
These phases include:
Initialization: Capability negotiation and protocol version agreement
Operation: Normal protocol communication
Shutdown: Graceful termination of the connection
The initialization phase establishes protocol compatibility and shares implementation details. This is when an AI Agent learns about available tools through schema definitions and receives instructions for tool usage. This initialization process is crucial to the solution, as it’s where AI Agents first discover what tools are available and how they should be used. During this phase, the client sends information about its protocol version, capabilities, and implementation details. This is how tools like Amazon Q CLI receive information about an MCP server’s version, available tools, and usage instructions.
Note: For more information on the MCP lifecycle, see these docs.
Solution – Token-Based Tool Orchestration: A New Pattern for AI Agents in MCP
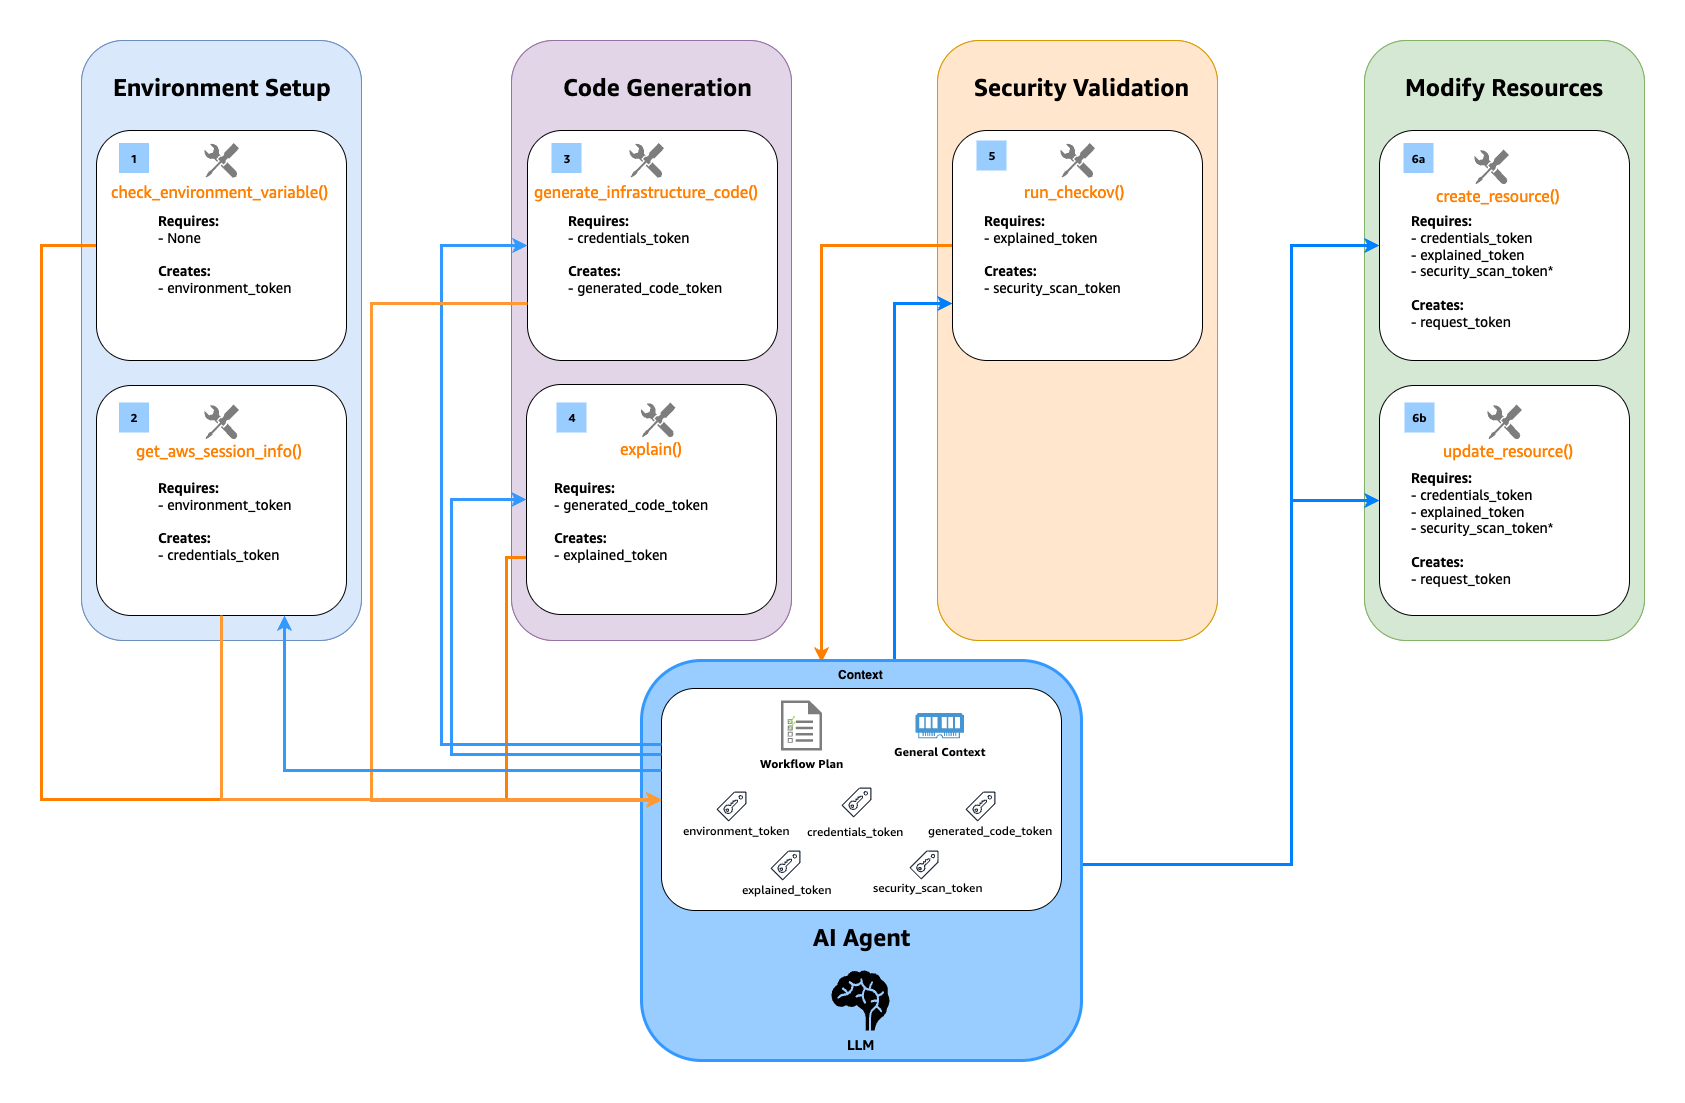
MCP presents a specific challenge: tools cannot directly communicate with each other to enforce execution order. The CCAPI MCP server addresses this through a token messenger pattern shown above, where the server generates and controls validation tokens, and the AI Agent (as the MCP client) passes these tokens between tool calls.
Core Implementation:
Function Enhancement – The mcp.tool() decorator transforms each function into a more capable entity. It wraps the function with a schema that defines required inputs and their validation rules, while preserving detailed documentation through docstrings. Each enhanced function clearly communicates its requirements and provides explicit error messages when dependencies aren’t met.
Dependency Discovery – During the initialize phase in the MCP lifecycle, the AI Agent (as the MCP client) receives a complete map of all defined tools and their schemas from the MCP server. The LLM, which is part of the AI Agent, uses these schemas to understand dependencies through both parameter descriptions and required input arguments. For instance, when a tool requires a parameter described as “Result from get_aws_session_info()” and defines security_scan_token as a required input argument, the LLM understands it needs both valid tokens before proceeding. This combination of descriptive text and explicit input requirements enables the AI Agent to execute sequences like get_aws_session_info() → generate_infrastructure_code() → run_checkov() → create_resource().
Token Validation Control –The server generates and controls all workflow tokens through a unified server-side storage system (_workflow_store). Each tool in the workflow generates cryptographically secure tokens, and these tokens are stored server-side with their associated data.
The AI Agent maintains these tokens in its conversation context throughout the workflow, passing them between tool calls. For security, each token used by the AI Agent must be validated against the server’s token storage. Since these tokens are short-lived, they are stored in memory (RAM) and are actively managed by the MCP server, which deletes tokens after use to maintain freshness. Any remaining tokens are automatically cleared when the server process ends or restarts. If a token doesn’t exist in the server’s storage (either because it’s invalid or already consumed), the operation fails immediately with an error. This validation is uniform across all token types, ensuring the AI Agent cannot create or modify tokens.
As the workflow progresses, tools consume existing tokens and generate new ones. For example, when explain() receives a properties_token, it first validates it exists and matches what is in _workflow_store, then consumes it and generates a new explained_properties_token. This creates a cryptographically secure chain of operations that enforces the workflow sequence (generate → scan → create), with server-side validation at every step.
The result is a predictable workflow system with strong security controls – tokens must be generated by the server and validated against server-side storage at each step, helping ensure the integrity of the infrastructure management process. This approach provides robust workflow enforcement within the confines of the current functionality of the FastMCP framework. While explicit schema-defined dependencies like @mcp.tool(depends_on=["run_checkov"]) as mentioned in this GitHub Issue would be ideal and could hopefully be added in future FastMCP versions, the current token-based approach with descriptive parameter names and clear validation provides reliable tool ordering that LLMs consistently follow without confusion.
Potential Limitations and Solutions
Session Management – When an AI Agent’s session ends or refreshes, any in-progress workflows must be restarted. This is by design – tokens are meant to be short-lived and tied to specific workflow sequences. AWS credentials naturally expire within hours as part of standard security practices, providing a natural boundary for workflow sessions.
Concurrent Workflows – Each AI Agent interaction operates independently, which is appropriate for maintaining security boundaries between different workflow instances. While this means each session starts fresh, it ensures clean separation between different infrastructure operations.
Implementation Options – For organizations requiring workflow persistence, traditional database storage could maintain session state between restarts. However, since tokens are designed to be short-lived security controls, most implementations can rely on the default in-memory storage with natural session boundaries.
The token messenger pattern provides a solid foundation for secure workflow orchestration, with its intentionally ephemeral tokens ensuring proper tool sequencing and data integrity during infrastructure operations.
The Future of MCP
While the above solution works, this process made me think about the future of MCP and how it can and should continue to grow. There are many updates to the framework I’ve seen recently, and it’s great to see activity. For Agentic AI in general, there are strong signs that the future of agentic platforms may be more deterministic in nature, as highlighted by Claude Code’s new support for lifecycle hooks. Per their docs, “Hooks provide deterministic control over Claude Code’s behavior, ensuring certain actions always happen rather than relying on the LLM to choose to run them.” For IaC and other deterministic technologies that it is desired to integrate AI with, this is essential for wide-scale adoption.
Conclusion
The journey of Model Control Protocol (MCP) and this new frontier of leveraging AI for managing cloud infrastructure continues to evolve, presenting both opportunities and challenges in the world of cloud computing and artificial intelligence. Current approaches using prompt loading and parameter dependencies have helped address initial challenges around tool ordering and security protocols, demonstrating how MCP can be effectively used in enterprise applications.
While the current implementation using workflow tokens and validation checks provides a functional solution, we continue to explore ways to enhance the protocol’s capabilities. For those interested in contributing to MCP’s evolution, you can find our proposals for protocol improvements, including enhanced dependency management, in the modelcontextprotocol GitHub org as well as in the FastMCP GitHub repository.
If you’d like to learn more about the AWS Cloud Control API MCP server mentioned in this blog, check out the documentation and GitHub repo. If you’d like to get hands on with it and other AWS MCP servers, check out this AWS workshop. Happy vibe coding my friends.
BPF programs are loaded directly into the kernel.
Even though the verifier protects the kernel from certain kinds of
misbehavior in BPF programs, some people are still justifiably concerned about
adding unsigned code to their kernel. A fully correct BPF program can still be
used to expose sensitive data, for example.
To remedy this, Blaise Boscaccy and KP Singh
have both shared patch sets that add ways to verify cryptographic
signatures of BPF programs, allowing users to configure their kernels to load
only pre-approved BPF programs. This work follows on from the
discussion at the
Linux Storage, Filesystem, Memory-Management, and BPF Summit (LSFMM+BPF)
in April and Boscaccy’s
earlier proposal of a Linux Security Module (LSM) to accomplish the same goal.
There are
still some fundamental disagreements over the best approach to signing BPF
programs, however.
The Arch Linux project is
especially well-known in the Linux community for two things: its
rolling-release model and the quality of the documentation in the ArchWiki. No
matter which Linux distribution one uses, the odds are that eventually
the ArchWiki’s documentation will prove useful. The Debian project
recognized this and has sought to improve its own documentation game
by inviting ArchWiki maintainers Jakub Klinkovský and Vladimir
Lavallade to DebConf25 in
Brest, France, to speak about how Arch manages its wiki. The talk has
already borne fruit with the launch of an effort to revamp the Debian
wiki.
Version 1.3.0 of
the Radicle distributed software forge system has been released. Changes
this time around include canonical
references, a new radicle-protocol crate, better log rotation,
and more. (LWN looked at Radicle in 2024).
Security updates have been issued by AlmaLinux (kernel, kernel-rt, and python-requests), Debian (ca-certificates-java), Fedora (chromium, clash-meta, mingw-python3, openjpeg, php-adodb, and toolbox), Mageia (kernel and kernel-linus), SUSE (chromium, ImageMagick, libgcrypt, libssh, libxml2, opensc, postgresql14, and postgresql16), and Ubuntu (dnsmasq, linux-gcp-6.8, linux-raspi, linux-oracle-6.14, and openjdk-17).
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.

 2. This will start initializing the MCP servers in the background, allowing you to immediately start using Q Chat even if they are still loading. As a note, if these have not finished loading, your prompts will be handled without using any MCP servers. To check the status of the servers, run