Tag Archives: announcements

Amazon MSK simplifies configuring custom domain names

Post Syndicated from Ali Alemi original https://aws.amazon.com/blogs/big-data/amazon-msk-simplifies-configuring-custom-domain-names/

Previously, you had to manually override the advertised listener on each broker and repeat it every time a broker was added. This approach was operationally heavy and could not be implemented on a cluster in KRaft mode. With Amazon Managed Streaming for Apache Kafka (Amazon MSK), you can now configure custom domain names for your Provisioned clusters using a single property. This works for clusters in both ZooKeeper and KRaft mode. Now you define the domain once and Amazon MSK applies it across every broker, so custom domain names keep working through scaling of the MSK cluster.

Custom domain names on Amazon MSK

Amazon MSK is a fully managed service for building and running applications that use Apache Kafka to process streaming data. By default, Amazon MSK brokers advertise addresses that AWS generates (for example, b-1.cluster-name.kafka.us-east-1.amazonaws.com) to connecting clients. These addresses are unique to each cluster and change when a cluster is recreated.

Many organizations need a static, customer-controlled endpoint that stays the same regardless of the underlying cluster. They achieve this with a custom domain name, so that they can:

  • Route traffic through Network Load Balancers (NLBs) when IP exhaustion forces clusters into non-routable subnets.
  • Avoid client reconfiguration during cluster migrations, so clients keep the same endpoint even when the underlying cluster changes.
  • Simplify disaster recovery (DR) failover, where the same domain fronts both primary and standby clusters.
  • Align with organizational naming, security, and compliance conventions.

Until now, the only way to do this was to override the advertised.listeners on each broker using the kafka-configs.sh --alter tool. It required carefully preserving every internal listener and re-running that override every time a broker was added. This works, but it accepts any string with no validation. A single typo can cause an outage. It requires manual, per-broker steps with no cluster-wide mechanism. It cannot be managed through infrastructure as code, and it could not be implemented on Amazon MSK brokers in KRaft mode. This blocked customers who rely on custom domain names from using them on KRaft-based clusters. With this launch, a single configuration property replaces all of that.

What you set up, and what Amazon MSK manages

A working custom domain name has two parts, and understanding this split up front helps the rest of this post make sense. You own the client connectivity and trust layer. Amazon MSK owns the cluster-side advertised listener configuration. The following diagram shows the client connectivity and trust layer.
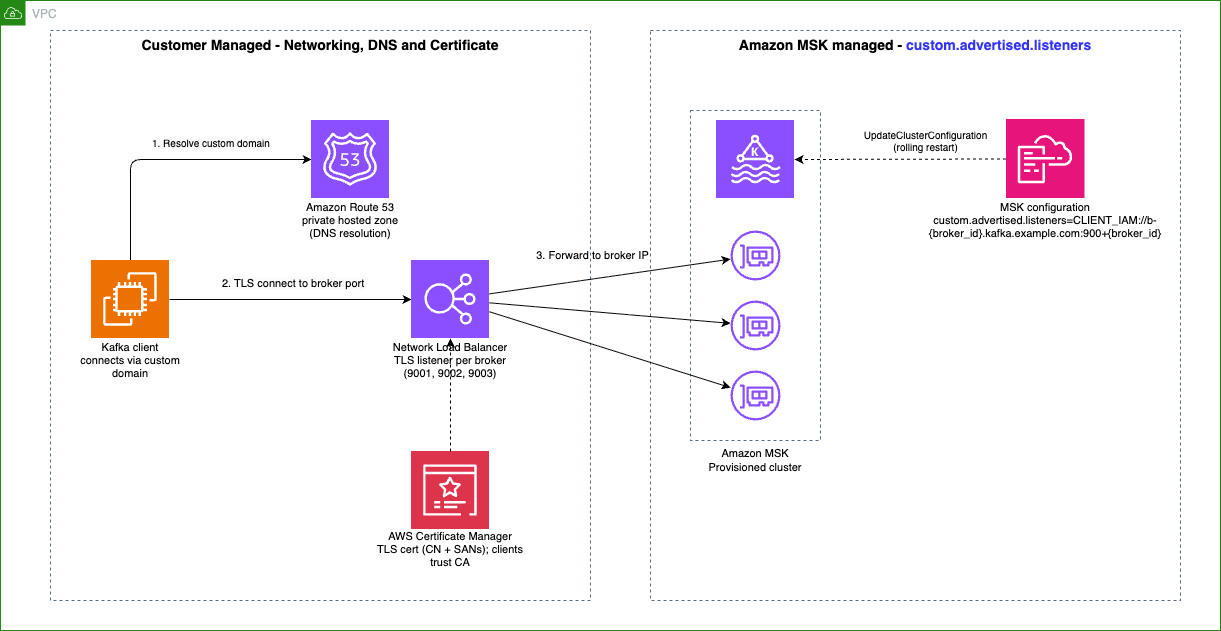
Diagram of the client connectivity and trust layer you manage and the advertised listener configuration Amazon MSK manages

Figure 1: The client connectivity and trust layer (left) is a prerequisite you own and manage. The advertised listener configuration on the cluster (right) is what Amazon MSK manages for you

Important: When you apply custom.advertised.listeners, your custom domain name replaces the default addresses that clients use to connect to broker nodes. If the networking and trust layer is not already in place, resolvable, reachable, and trusted from the client, the client cannot reconnect, even though it was connected moments earlier.

Part 1: The client connectivity and trust layer (you manage)

The Prerequisites section below shows the key requirements. You can find the detailed setup in an existing post, Configure a custom domain name for your Amazon MSK cluster, which includes a diagrammed walkthrough of the NLB, Amazon Route 53, and AWS Certificate Manager (ACM) topology.

Part 2: The advertised listener configuration (Amazon MSK managed)

After the connectivity layer exists, you tell the brokers which custom address to advertise to clients. This is the part that used to require a per-broker CLI override, and it is what this launch simplifies. This next section describes how it works.

Prerequisites

Before a client can reach your brokers through a custom domain, the connectivity and trust path must exist. You create and manage this layer. It covers three things:

  • Networking: A network gateway, like a Network Load Balancer (NLB), TLS certificate, DNS records, and security groups that route traffic from your custom domain to your broker IPs.
  • Certificate trust: The client’s truststore must include certificate authorities in the path (the load balancer’s custom-domain cert).
  • DNS resolution: Clients must resolve the custom domain to your NLB, typically through an Amazon Route 53 private hosted zone associated with the client virtual private cloud (VPC).

This layer must be in place for custom domain names to function. It is a prerequisite for this feature to work.

How it works

You add a property to your Amazon MSK configuration. The value takes the form:

custom.advertised.listeners=<LISTENER>://<hostname>:<port>

where <LISTENER> is one of your cluster’s client listeners and <hostname>:<port> is the custom address pattern. For example, on an IAM cluster:

custom.advertised.listeners=CLIENT_IAM://b-{broker_id}.example.com:9000+{broker_id}

The property specifies two things:

  1. Each listener corresponds to an authentication type on your cluster. Custom advertised endpoints can be set only for client listeners: CLIENT, CLIENT_SECURE, CLIENT_SECURE_PUBLIC, CLIENT_SASL_SCRAM, CLIENT_SASL_SCRAM_PUBLIC, CLIENT_IAM, and CLIENT_IAM_PUBLIC. Internal listeners (REPLICATION, CONTROLLER) are not supported and are rejected at validation. The listener you specify must also be bound (active) on your cluster. For example, if your cluster uses only IAM authentication, specifying CLIENT_SECURE is rejected, and the error message lists the valid client listeners for your cluster.
  2. A custom hostname:port pattern that includes the {broker_id} template variable. Each broker resolves to a unique address. In this pattern, the {broker_id} template variable is replaced with each broker’s numeric ID. The port number 9000+{broker_id} means the broker ID is added to the base port 9000, so broker 1 resolves to 9001, broker 2 to 9002, broker 10 to 9010, and so on. The base port 9000 is only an example. You can use any base port, as long as the resulting ports match the TLS listeners you provisioned on your NLB.

{broker_id} can appear in the hostname, the port, or both, as long as each broker’s resolved host:port is unique. Placing it in the port alone is valid, so a shared hostname with a per-broker port also works:

custom.advertised.listeners=CLIENT_IAM://example.com:9000+{broker_id}

Before you begin, you need an MSK configuration to hold this property. You create one with the CreateConfiguration API (or the AWS Management Console), passing your server properties as the configuration body. MSK returns a configuration ARN and a revision number, which together identify the exact configuration you apply to the cluster.

custom.advertised.listeners does not need its own standalone configuration. You can include it alongside any other broker-level properties MSK already supports, such as auto.create.topics.enable, num.partitions, or log-retention settings, within a single configuration revision. If you already manage an MSK configuration for your cluster, add custom.advertised.listeners to it and create a new revision using the UpdateConfiguration API. No separate configuration is needed.

You then apply the configuration to your cluster with the UpdateClusterConfiguration API. Amazon MSK then performs three actions:

  • Validates the configuration.
  • Resolves the pattern for each broker.
  • Applies it through a rolling restart across the cluster.

These safeguards prevent you from accidentally removing or modifying the internal listeners that Amazon MSK manages. Validation is synchronous. The listener must be a client-facing listener, the pattern must include {broker_id}, and each broker’s resolved host:port must be unique. If any check fails, the API returns a descriptive error and makes no change.

The override affects only the advertised address of the named listener. Replication, authentication, multi-VPC (CLIENT_IAM_VPCE), and AWS PrivateLink connectivity remain unaffected. The change is also fully reversible: remove the custom.advertised.listeners property and re-apply the configuration, and Amazon MSK reverts the listener to its original address.

You can track progress with the DescribeOperation API, which shows state transitions from UPDATE_IN_PROGRESS to UPDATE_COMPLETE or UPDATE_FAILED. If a broker fails to start, the rollout halts at that broker, the remaining brokers keep their previous configuration, and you can fix the property and re-apply to recover.

Setting up a custom domain name end to end

When you apply custom.advertised.listeners, your custom domain name replaces the default addresses that clients use to connect to broker nodes. If the networking and trust layer is not already in place, resolvable, reachable, and trusted from the client, the client cannot reconnect, even though it was connected moments earlier.

The networking layer, the Network Load Balancer (NLB), DNS, and TLS certificate that route traffic from your custom domain to your broker IPs, is a prerequisite you own. It is not specific to this launch. The existing post Configure a custom domain name for your Amazon MSK cluster covers it in detail, with a diagrammed walkthrough of the NLB, Route 53, and ACM topology. With the networking in place, the following steps cover the cluster-side setup this launch introduces.

Step 1: Add the custom domain to your Amazon MSK configuration

Create or update an Amazon MSK configuration that includes the custom.advertised.listeners property, matching the hostnames and ports you provisioned on the NLB. For a three-broker IAM cluster fronted by an NLB with ports 9001–9003, put the property in a file:

custom.advertised.listeners=CLIENT_IAM://b-{broker_id}.example.com:9000+{broker_id}

Then create the configuration, passing the file as the server properties:

aws kafka create-configuration \
    --name "custom-domain-iam" \
    --description "Custom advertised listeners for CLIENT_IAM" \
    --server-properties fileb://custom-domain-config.txt

Use fileb:// (not file://) so the CLI reads the file as bytes and base64-encodes it. Passing the value inline is fragile because of the {broker_id} braces. Leave {broker_id} literal in the file. Amazon MSK resolves it per broker at apply time. The response returns the configuration ARN and LatestRevision.Revision, which you use in the next step.

Step 2: Apply the configuration

Apply the configuration to your cluster with UpdateClusterConfiguration, using the console, AWS Command Line Interface (AWS CLI), AWS CloudFormation, CDK, or Terraform. This is the same workflow you already use for broker configuration changes.

aws kafka update-cluster-configuration \
    --cluster-arn <your-cluster-arn> \
    --configuration-info arn=<configuration-arn>,revision=<revision> \
    --current-version <current-cluster-version>

If the configuration fails to apply, review the errors. For details, see the troubleshooting section in the Amazon MSK Developer Guide.

Step 3: Track the rollout

aws kafka describe-cluster-operation-v2 \
    --cluster-operation-arn <operation-arn>

After the configuration is accepted, Amazon MSK applies it through a rolling restart. Wait until the operation reports SUCCESS. If it reports FAILED, a broker could not apply the change. The rollout halts at that broker, the remaining brokers keep their previous configuration, and you can fix the configuration and re-apply to recover.

Step 4: Verify

Confirm clients can connect through the custom domain:

kafka-topics.sh --list --bootstrap-server b-1.example.com:9001

If your topic list is returned, clients are successfully connecting through your custom domain. If the operation reported SUCCESS but clients cannot connect, the cluster-side configuration is correct, but your networking layer likely needs attention.

Client connectivity during rollout

This step is important. Clients can be disconnected if the networking is not ready. Kafka clients do not keep using the original address they bootstrapped with. On a periodic metadata refresh, each client learns the broker’s advertised listener. The client uses that address for all subsequent connections. When you apply a custom domain name, that advertised address changes from the default name that Amazon MSK generates to your custom domain, so at the next metadata refresh every client connects over the custom domain. For this reason, the connectivity and trust layer described in What you set up, and what Amazon MSK manages is a prerequisite, not a follow-up task.

The safe sequence, which is also how customers move from Amazon DNS to a custom domain today, is two phases:

  1. Build the networking path first: Stand up the NLB, DNS, and certificate, and point your clients at the custom bootstrap endpoint, but do not set the advertised listener yet. Clients bootstrap through the custom endpoint while still connecting to brokers over the addresses that Amazon MSK generates.
  2. Configure the advertised listener: With the path already in place, applying custom.advertised.listeners changes what the brokers advertise. At the next metadata refresh, clients pick up the custom domain and cut over to it automatically.

Because the path already exists, this cutover is transparent: as Amazon MSK applies the change broker by broker, clients reconnect on their own, with no restart or reconfiguration.

Scaling and replacement of brokers

When you scale the cluster or a broker is replaced during automated healing, Amazon MSK automatically applies the configuration to the new broker, resolving {broker_id} for its ID, with no manual steps required on the cluster side. Remember to add the corresponding NLB listener, target group, and DNS record for any new broker, because the networking layer does not auto-scale.

Conclusion

Custom domain name configuration turns a per-broker CLI workaround into a single, validated, cluster-wide Amazon MSK configuration property. It works identically on ZooKeeper and KRaft, persists through scaling and failover, and flows through your existing Terraform, CloudFormation, and CLI workflows. If you rely on custom domain names, we recommend adopting the static configuration now.

This capability is available on all Amazon MSK Provisioned clusters with Standard and Express brokers, in all AWS Regions where Amazon MSK Provisioned is available. To get started, see the Amazon MSK Developer Guide and the end-to-end networking walkthrough in Configure a custom domain name for your Amazon MSK cluster.
About the authors

Ali Alemi

Ali Alemi

Ali is a Streaming Specialist Solutions Architect at AWS. Ali advises AWS customers with architectural best practices and helps them design real-time analytics data systems. Prior to joining AWS, Ali supported several public sector customers and AWS consulting partners in their application modernization journey and migration to the cloud.

Subham Rakshit

Subham Rakshit

Subham is a Streaming Specialist Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build search and streaming data platforms that help them achieve their business objective. Outside of work, he enjoys spending time solving jigsaw puzzles with his daughter.

OAuth 2.0, LDAP, and HTTP auth for Amazon MQ for RabbitMQ

Post Syndicated from Vinodh Kannan Sadayamuthu original https://aws.amazon.com/blogs/big-data/oauth-2-0-ldap-and-http-auth-for-amazon-mq-for-rabbitmq/

This is Part 2 of a three-part series on authentication and authorization for Amazon MQ for RabbitMQ. For an overview of all available methods, see Authentication and Authorization Options for Amazon MQ for RabbitMQ. For certificate-based mTLS and SSL authentication, see Part 1. For AWS Identity and Access Management (IAM) authentication, see Part 3.

When you deploy Amazon MQ for RabbitMQ in an enterprise environment, authentication quickly becomes more complex than a single broker configuration. Your organization might already have an Active Directory managing thousands of users, or a cloud identity provider handling application access, or workloads that require short-lived, token-based credentials. Maintaining a separate set of static RabbitMQ credentials alongside these systems creates operational overhead and introduces security gaps. This is especially true when users change roles, leave the organization, or when credentials need to be rotated across multiple brokers.

Amazon MQ for RabbitMQ supports OAuth 2.0, LDAP, and HTTP-based authentication backends, so you can connect your broker directly to the identity infrastructure you already use. This post explains how each approach works, highlights the key configurations, and helps you decide which one fits your use case.

Overview

This post covers three authentication and authorization integrations for Amazon MQ for RabbitMQ:

  1. OAuth 2.0: Token-based authentication where clients obtain short-lived tokens from an identity provider and present them to the broker as bearer credentials. The broker validates tokens using JSON Web Key Sets (JWKS) and derives permissions from token scopes.
  2. LDAP: Directory-based authentication where the broker delegates credential verification to an LDAP directory such as Active Directory. Users authenticate with their directory credentials, and RabbitMQ permissions map to LDAP group memberships.
  3. HTTP authentication backend: A flexible approach where the broker delegates authentication and authorization decisions to an external HTTP service, so you can implement custom logic or integrate with identity systems that don’t support OAuth 2.0 or LDAP natively.

All three approaches eliminate the need to manage broker-local credentials. They provide centralized user management, fine-grained access control, and audit capabilities through your existing identity infrastructure.

How OAuth 2.0 authentication works

OAuth 2.0 authentication eliminates static broker credentials by using short-lived tokens issued by an external identity provider. Instead of storing usernames and passwords in the broker, clients obtain access tokens and present them as credentials when connecting.

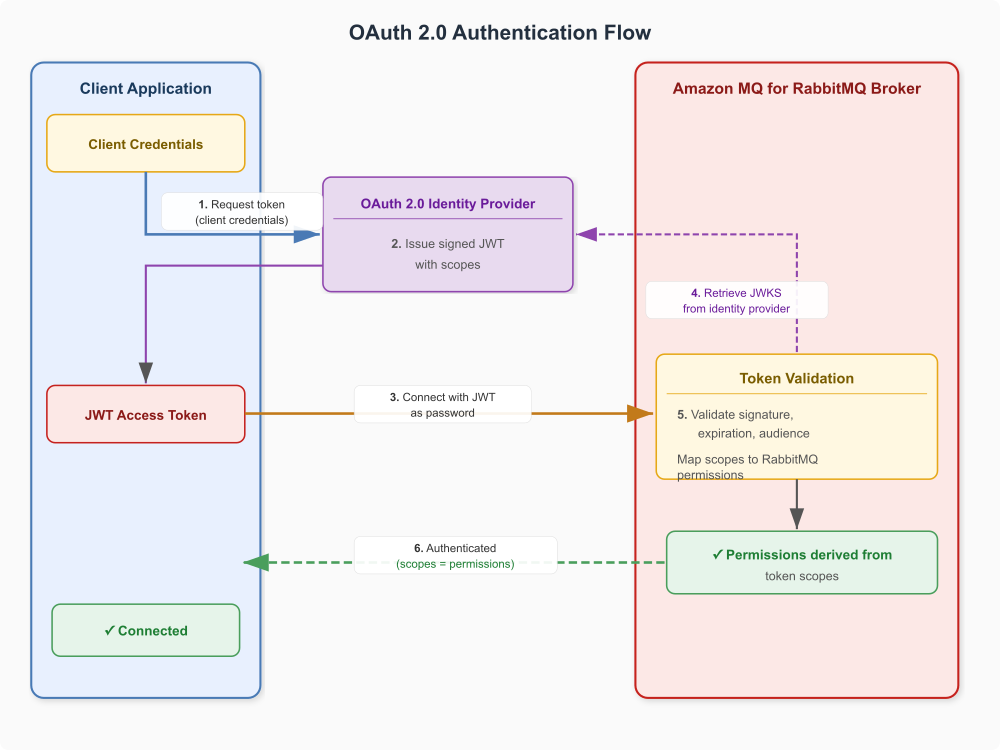
When a client connects to a broker configured with OAuth 2.0 authentication:

  1. The client requests an access token from the OAuth 2.0 identity provider, specifying the required scopes.
  2. The identity provider validates the client credentials and issues a signed JWT (JSON Web Token) containing the granted scopes.
  3. The client connects to the Amazon MQ broker and presents the JWT as the password.
  4. The broker retrieves the identity provider’s public keys through the JWKS endpoint.
  5. The broker validates the token signature, expiration, and audience claim.
  6. The broker extracts RabbitMQ permissions from the token scopes and grants access accordingly.

The following diagram shows the OAuth 2.0 authentication flow.

OAuth 2.0 authentication flow between a client, an identity provider, and the Amazon MQ for RabbitMQ broker

Figure 1: OAuth 2.0 authentication flow for Amazon MQ for RabbitMQ

Scope-to-permission mapping

The broker maps OAuth 2.0 scopes to RabbitMQ permissions using a configurable prefix. For example, with the resource server ID rabbitmq, the following scopes grant specific access:

OAuth 2.0 scope RabbitMQ permission
rabbitmq.read:*/* Read access to all resources in all vhosts
rabbitmq.write:*/* Write access to all resources in all vhosts
rabbitmq.configure:*/* Configure access to all resources in all vhosts
rabbitmq.read:orders/* Read access to all resources in the orders vhost
rabbitmq.tag:management Management UI access
rabbitmq.tag:administrator Administrator access

Key configuration

The following rabbitmq.conf snippet shows the essential settings for OAuth 2.0 authentication:

# Enable OAuth 2.0 authentication (with internal fallback for the monitoring user)
auth_backends.1 = oauth2
auth_backends.2 = internal

# OAuth 2.0 resource server configuration
auth_oauth2.resource_server_id = rabbitmq
auth_oauth2.preferred_username_claims.1 = sub

# JWKS endpoint for token validation
auth_oauth2.jwks_uri = https://your-idp.example.com/.well-known/jwks.json

# Additional token validation
auth_oauth2.issuer = https://your-idp.example.com
auth_oauth2.scope_prefix = rabbitmq.

# Skip audience validation for IdPs that do not emit an aud claim matching resource_server_id
auth_oauth2.verify_aud = false

The following table describes each configuration setting.

Setting Purpose
auth_backends.1 = oauth2 Enables the OAuth 2.0 authentication backend (use auth_backends.2 = internal for the monitoring user fallback)
auth_oauth2.resource_server_id Identifies this broker as a resource server. Used as the scope prefix
auth_oauth2.preferred_username_claims.1 JWT claim used to extract the username for display and logging
auth_oauth2.jwks_uri URL of the identity provider’s JWKS endpoint for token signature validation (named jwks_url on RabbitMQ 3.x, jwks_uri on 4.x)
auth_oauth2.issuer Expected token issuer. Tokens from other issuers are rejected
auth_oauth2.verify_aud Whether the broker validates the token’s aud claim against resource_server_id. Set to false for IdPs that do not emit a matching aud
auth_oauth2.scope_prefix Prefix applied to scopes when mapping to RabbitMQ permissions

Important considerations

  1. By default the broker validates the token’s aud (audience) claim against the resource_server_id and rejects tokens without a match. Some identity providers (for example, Amazon Cognito) don’t emit an aud claim matching the resource server. For those, set auth_oauth2.verify_aud = false.
  2. If your identity provider cannot issue scopes in the native RabbitMQ form (for example, it disallows the * wildcard), use auth_oauth2.scope_aliases entries to translate the provider’s scope names to RabbitMQ scopes such as rabbitmq.read:*/*.
  3. Configure short-lived tokens (one hour or less) and implement token refresh logic in your client applications.
  4. The JWKS endpoint must be reachable from the broker’s network. For private identity providers, verify network connectivity and DNS resolution.
  5. On RabbitMQ 3.x the JWKS endpoint setting is auth_oauth2.jwks_url. On RabbitMQ 4.x it is auth_oauth2.jwks_uri. Use the setting name that matches your broker engine version.
  6. Amazon MQ automatically creates a system user named monitoring-AWS-OWNED-DO-NOT-DELETE with monitoring-only permissions. This user uses the internal RabbitMQ authentication system even on OAuth 2.0-enabled brokers.

How LDAP authentication works

LDAP authentication connects your RabbitMQ broker to an existing directory service such as Active Directory. Instead of managing users locally in the broker, the broker delegates authentication to the LDAP server and derives permissions from directory group memberships. This centralizes user management and lets you apply your existing password policies, account lockout rules, and audit trails to broker access.

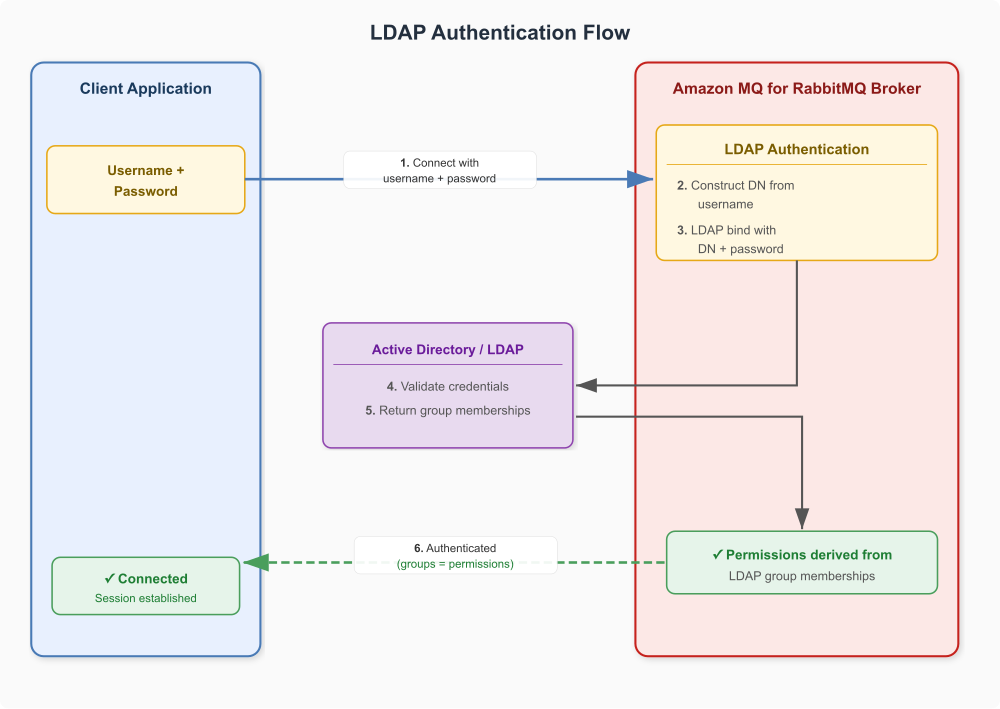
When a client connects to a broker configured with LDAP authentication:

  1. The client connects to the Amazon MQ broker with a username and password.
  2. The broker constructs a Distinguished Name (DN) from the username using the configured user_dn_pattern.
  3. The broker performs an LDAP bind operation against the directory server using the constructed DN and the client’s password.
  4. If the bind succeeds, the broker queries the directory for the user’s group memberships.
  5. The broker maps group memberships to RabbitMQ permissions (vhost access, resource permissions, and management tags).
  6. The client is authenticated and authorized based on the LDAP query results.

The following diagram shows the LDAP authentication flow.

LDAP authentication flow showing the Amazon MQ broker binding to a directory server and mapping group memberships to permissions

Figure 2: LDAP authentication flow for Amazon MQ for RabbitMQ

LDAP directory structure

This implementation uses a group-centric LDAP model where RabbitMQ concepts (vhosts, exchanges, queues, and tags) are represented as sub-OUs under a single groups hierarchy:

OU=rabbitmq
├── OU=users
│   ├── CN=app-orders-producer
│   └── CN=app-orders-consumer
│
└── OU=groups
    ├── OU=vhosts
    │   ├── CN=vhost-orders
    │   └── CN=vhost-payments
    │
    ├── OU=exchanges
    │   ├── CN=orders-publisher
    │   └── CN=payments-publisher
    │
    ├── OU=queues
    │   ├── CN=orders-consumer
    │   └── CN=payments-consumer
    │
    └── OU=tags
        ├── CN=rmq-admin
        └── CN=rmq-monitor

Users are assigned to groups based on their required access. For example, app-orders-producer would be a member of vhost-orders and orders-publisher, granting it access to the orders vhost and write permissions on the orders exchange.

Key configuration

The following rabbitmq.conf snippet shows the essential settings for LDAP authentication:

# Enable LDAP as primary backend with internal as fallback
auth_backends.1 = ldap
auth_backends.2 = internal

# LDAP server connection (LDAPS on port 636)
auth_ldap.servers.1 = your-active-directory-server.example.com
auth_ldap.port = 636
auth_ldap.user_dn_pattern = CN=${username},OU=users,OU=rabbitmq,DC=example,DC=com
auth_ldap.use_ssl = true
auth_ldap.ssl_options.verify = verify_peer
auth_ldap.log = true

# AWS integration: assume an IAM role to retrieve the CA certificate for LDAPS
aws.arns.assume_role_arn = arn:aws:iam::111122223333:role/AmazonMqLdapRole
aws.arns.auth_ldap.ssl_options.cacertfile = arn:aws:s3:::your-ca-cert-bucket/ca-cert.pem

# Management console tags
auth_ldap.queries.tags = '''
[{administrator, {in_group, "CN=rmq-admin,OU=tags,OU=groups,OU=rabbitmq,DC=example,DC=com"}},
{management, {in_group, "CN=rmq-monitor,OU=tags,OU=groups,OU=rabbitmq,DC=example,DC=com"}}]
'''

# Vhost access control
auth_ldap.queries.vhost_access = '''
{in_group, "CN=vhost-${vhost},OU=vhosts,OU=groups,OU=rabbitmq,DC=example,DC=com"}
'''

# Resource access control
auth_ldap.queries.resource_access = '''
{for, [{permission, configure,
{in_group, "CN=rmq-admin,OU=tags,OU=groups,OU=rabbitmq,DC=example,DC=com"}},
{permission, write,
{for, [{resource, exchange,
{in_group, "CN=orders-publisher,OU=exchanges,OU=groups,OU=rabbitmq,DC=example,DC=com"}}]}},
{permission, read,
{for, [{resource, queue,
{in_group, "CN=orders-consumer,OU=queues,OU=groups,OU=rabbitmq,DC=example,DC=com"}}]}}]}
'''

The following table describes each configuration setting.

Setting Purpose
auth_backends.1 = ldap Sets LDAP as the primary authentication backend
auth_backends.2 = internal Falls back to internal authentication if LDAP is unavailable
auth_ldap.servers.1 LDAP server hostname or IP address
auth_ldap.user_dn_pattern Template for constructing the user DN from the provided username
auth_ldap.port LDAP server port; 636 for LDAPS
auth_ldap.use_ssl Enables an encrypted LDAPS connection to the directory server. Amazon MQ requires that you explicitly set either auth_ldap.use_ssl = true or auth_ldap.use_starttls = true. The broker fails configuration validation if neither is set.
auth_ldap.ssl_options.verify Certificate verification mode for the LDAPS connection. Verify_peer validates the server certificate
aws.arns.assume_role_arn ARN of the IAM role the broker assumes to retrieve the CA certificate
aws.arns.auth_ldap.ssl_options.cacertfile ARN of the CA certificate (in S3) used to validate the LDAP server’s TLS certificate
auth_ldap.queries.tags Maps directory group membership to the administrator and management console tags
auth_ldap.queries.vhost_access LDAP query that determines which vhosts a user can access based on group membership
auth_ldap.queries.resource_access LDAP query that determines resource-level permissions (configure, write, read) based on group membership

Important considerations

  1. Amazon MQ requires an encrypted LDAP connection: you must explicitly set either auth_ldap.use_ssl = true (LDAPS on port 636) or auth_ldap.use_starttls = true (StartTLS on port 389). The broker rejects the configuration if neither is set. Unencrypted LDAP transmits credentials in plaintext, so always use one of these options to protect credentials in transit between the broker and your directory server.
  2. The user_dn_pattern must match your directory’s organizational structure exactly. Verify the pattern with an LDAP browser before applying it to the broker.
  3. With Active Directory, user DNs are usually based on the display name rather than the sign-in name, so a fixed user_dn_pattern often will not match. In that case, configure DN lookup (auth_ldap.dn_lookup_bind, auth_ldap.dn_lookup_base, and auth_ldap.dn_lookup_attribute = sAMAccountName) so the broker resolves each username to its full DN before binding.
  4. LDAP configuration changes require a broker reboot to take effect. However, user permission changes in the directory (group membership additions or removals) take effect immediately for new connections.
  5. Configure the internal backend as a fallback to maintain access if the LDAP server becomes temporarily unavailable.

How HTTP authentication works

The HTTP authentication backend delegates all authentication and authorization decisions to an external HTTP service. When a client connects, the broker sends requests over HTTPS to your service, which responds with allow or deny decisions. Amazon MQ requires encrypted connections and rejects any configuration that uses a plain http endpoint. This approach provides maximum flexibility for integrating with identity systems that don’t support OAuth 2.0 or LDAP natively, or when you need custom authentication logic. The HTTP authentication backend is available on Amazon MQ for RabbitMQ version 4 and above.

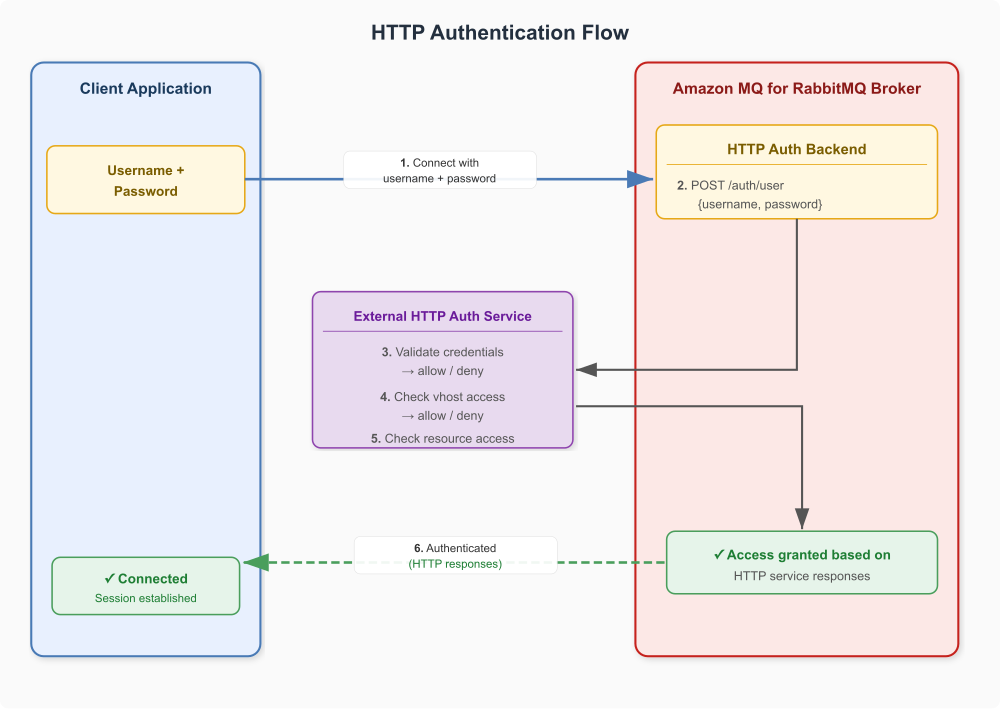
When a client connects to a broker configured with HTTP authentication:

  1. The client connects to the Amazon MQ broker with a username and password.
  2. The broker sends an HTTPS POST request to the configured authentication endpoint with the username and password.
  3. The external authentication service validates the credentials against its identity store and responds with allow or deny.
  4. For each authorization check (vhost access, resource permissions, topic permissions), the broker sends additional HTTPS requests to the corresponding endpoints.
  5. The authentication service evaluates the authorization request and responds with allow, deny, or allow with tags.
  6. The client is authenticated and authorized based on the authentication service responses.

The following diagram shows the HTTP authentication flow.

HTTP authentication flow showing the Amazon MQ broker sending credential and authorization checks to an external HTTP service

Figure 3: HTTP authentication flow for Amazon MQ for RabbitMQ

The broker sends HTTPS POST requests to four endpoints. Each endpoint must return a plain-text response:

Endpoint Request parameters Expected response
/auth/user username, password allow [tag1, tag2] or deny
/auth/vhost username, vhost, ip allow or deny
/auth/resource username, vhost, resource, name, permission allow or deny
/auth/topic username, vhost, resource, name, permission, routing_key allow or deny

Key configuration

The following rabbitmq.conf snippet shows the essential settings for HTTP authentication:

# Enable the HTTP backend with caching to reduce load on the auth service
auth_backends.1 = cache
auth_backends.2 = http
auth_cache.cached_backend = http

# HTTP authentication endpoints (HTTPS required)
auth_http.http_method = post
auth_http.user_path = https://your-auth-service.example.com/auth/user
auth_http.vhost_path = https://your-auth-service.example.com/auth/vhost
auth_http.resource_path = https://your-auth-service.example.com/auth/resource
auth_http.topic_path = https://your-auth-service.example.com/auth/topic

# TLS configuration for the HTTPS connection to the auth service
auth_http.ssl_options.verify = verify_peer
auth_http.ssl_options.sni = your-auth-service.example.com

# AWS integration: IAM role and CA certificate for secure credential retrieval
aws.arns.assume_role_arn = <your-assume-role-arn>
aws.arns.auth_http.ssl_options.cacertfile = <your-ca-cert-arn>

The following table describes each configuration setting.

Setting Purpose
auth_backends.1 = cache auth_backends.2 = http Enables the HTTP authentication backend with a cache layer in front, which reduces the number of calls to your authentication service
auth_http.user_path URL the broker calls to authenticate users
auth_http.vhost_path URL the broker calls to check vhost access
auth_http.resource_path URL the broker calls to check resource permissions (queues, exchanges)
auth_http.topic_path URL the broker calls to check topic-level permissions
auth_http.http_method HTTP method the broker uses to call the endpoints. Set to post
auth_http.ssl_options.verify Certificate verification mode for the HTTPS connection to the auth service. Verify_peer validates the server certificate
auth_http.ssl_options.sni Server Name Indication hostname sent during the TLS handshake with the auth service
aws.arns.assume_role_arn ARN of the IAM role the broker assumes to securely retrieve the CA certificate
aws.arns.auth_http.ssl_options.cacertfile ARN of the CA certificate the broker uses to validate the auth service’s TLS certificate

Important considerations

  1. The HTTP authentication service must be highly available. If the service is unreachable, all authentication attempts fail. Consider deploying it behind a load balancer with health checks.
  2. HTTPS is mandatory for all authentication endpoints. The broker rejects any endpoint configured with a plain http URL, ensuring credentials are always protected in transit.
  3. Front the HTTP backend with the cache backend (auth_backends.1 = cache) to reduce the number of calls to your authentication service and improve connection latency. Also keep your service’s response times low to avoid connection timeouts and degraded broker performance.
  4. The authentication service receives plaintext passwords. Make sure the service handles credentials securely and doesn’t log them.
  5. The broker connects to your authentication service over TLS. Configure certificate validation with auth_http.ssl_options.verify = verify_peer, and provide the CA certificate and the IAM role for retrieving it through the aws.arns.auth_http.ssl_options.cacertfile and aws.arns.assume_role_arn settings.

Implementation guides

For step-by-step deployment and validation instructions, see the following resources:

  1. Amazon MQ for RabbitMQ OAuth 2.0 authentication – Configure OAuth 2.0 token-based authentication for Amazon MQ.
  2. Amazon MQ for RabbitMQ LDAP integration – Configure LDAP directory integration for Amazon MQ.
  3. Amazon MQ for RabbitMQ HTTP authentication backend – Configure the HTTP authentication backend for Amazon MQ.
  4. Amazon MQ samples repository – AWS Cloud Development Kit (AWS CDK) stacks and sample code for LDAP and OAuth 2.0 integrations.

Conclusion

This post explained how OAuth 2.0, LDAP, and HTTP authentication backends work for Amazon MQ for RabbitMQ, and when to use each one. OAuth 2.0 provides token-based, passwordless authentication with automatic credential expiration. LDAP connects your broker to existing directory infrastructure for centralized user and group management. The HTTP backend offers maximum flexibility for custom identity integrations. Used individually or in combination, these approaches eliminate broker-local credential management and provide centralized access control through your existing identity infrastructure.

In the next post in this series, we cover IAM authentication and OAuth 2.0 authorization for Amazon MQ for RabbitMQ.

For more information about Amazon MQ security, see the following resources:

  1. Amazon MQ Developer Guide: Security
  2. RabbitMQ OAuth 2.0 plugin documentation
  3. RabbitMQ LDAP plugin documentation
  4. Amazon MQ samples repository

If you have questions or feedback about this post, leave a comment in the Comments section. For troubleshooting help, visit the AWS re:Post community for Amazon MQ.


About the authors

Vinodh Kannan Sadayamuthu

Vinodh Kannan Sadayamuthu

Vinodh is a Senior Specialist Solutions Architect at Amazon Web Services (AWS). His expertise centers on AWS messaging and streaming services, where he provides architectural best practices consultation to AWS customers.

Sarath Kumar Kallayil Sreedharan

Sarath Kumar Kallayil Sreedharan

Sarath Kumar K.S. is a Senior Technical Account Manager/Enterprise Support lead at Amazon Web Services. Sarath works with enterprise customers to help them architect and build highly reliable and cost-effective solutions on AWS. He specializes in serverless, messaging technologies, and AI services, and has a background in application development and architecture. In his spare time, he enjoys reading, traveling, playing cricket, and spending time with his family

Mutual TLS and SSL certificate authentication for Amazon MQ for RabbitMQ

Post Syndicated from Harshith Mithamar original https://aws.amazon.com/blogs/big-data/mutual-tls-and-ssl-certificate-authentication-for-amazon-mq-for-rabbitmq/

This is Part 1 of a three-part series on authentication and authorization for Amazon MQ for RabbitMQ. For an overview of all available methods, see Authentication and Authorization Options for Amazon MQ for RabbitMQ. For OAuth 2.0, LDAP, and HTTP authentication, see Part 2. For IAM authentication, see Part 3.

When you use Amazon MQ for RabbitMQ to handle sensitive data, standard TLS encryption alone might not meet your compliance requirements. Compliance frameworks like SOX, HIPAA, and PCI DSS often require verification of the identity of both parties in a connection. Features like mutual TLS (mTLS) and SSL certificate authentication can help support those requirements by adding certificate-based identity verification to your messaging infrastructure.

Amazon MQ for RabbitMQ version 4 or later supports two certificate-based security features that address these needs: SSL certificate authentication for passwordless certificate-only login, and mTLS for certificate-based peer verification with username and password authentication. This post explains how each approach works, highlights the key configuration options, and helps you decide which one fits your use case.

Overview

This post covers two certificate-based security features for Amazon MQ for RabbitMQ:

  1. SSL certificate authentication: Passwordless authentication where clients authenticate solely using X.509 client certificates through the EXTERNAL SASL mechanism. The broker extracts the username directly from the certificate, eliminating the need for passwords.
  2. Mutual TLS (mTLS): Certificate-based peer verification where both the client and broker prove their identities using certificates, while clients still authenticate with a username and password. This secures AMQP connections and the RabbitMQ management interface.

Both features are available for Amazon MQ for RabbitMQ version 4 and above, and both use AWS ARNs for certificate and credential references, integrating with AWS Certificate Manager (ACM), and AWS Identity and Access Management (IAM).

How SSL certificate authentication works

SSL certificate authentication eliminates the need to transmit credentials during connection. The broker extracts the client’s identity from the certificate, though the corresponding user must exist in RabbitMQ’s internal store for authorization. Instead of using certificates only for transport-layer verification, the broker uses the EXTERNAL SASL mechanism to extract the client’s identity directly from the X.509 certificate.

When a client connects to a broker configured with SSL certificate authentication:

  1. The client initiates a TLS connection and presents its client certificate.
  2. The Amazon MQ broker assumes an IAM role to retrieve the CA certificate from ACM.
  3. The broker validates the client certificate against the configured CA certificate.
  4. The broker extracts the username from the client certificate using the configured field (Common Name, Distinguished Name, or Subject Alternative Name).
  5. The broker authenticates the client using the extracted username. No password required.

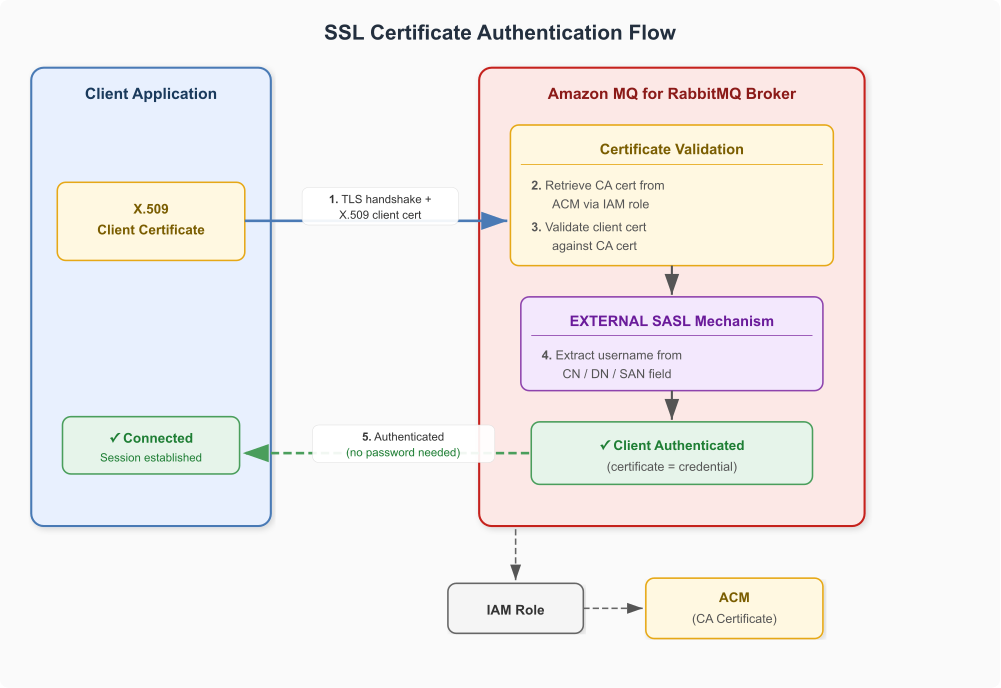
The following diagram shows the SSL certificate authentication flow. On the left, the client application holds only an X.509 client certificate with no credentials. In the center, the arrows show the TLS handshake carrying the client certificate to the broker, and the return path confirming authentication with no password needed. On the right, the Amazon MQ for RabbitMQ broker performs certificate validation, assuming an IAM role to retrieve the CA certificate from ACM. It then uses the EXTERNAL SASL mechanism to extract the username from the certificate’s CN, DN, or SAN field and establishes the authenticated session.

Client authenticates to the Amazon MQ for RabbitMQ broker using only an X.509 certificate through the EXTERNAL SASL mechanism, with no password

Figure 1: SSL certificate authentication flow

Username extraction options

The broker can extract the client identity from different fields of the X.509 certificate:

ssl_cert_login_from value Certificate field used Example
common_name Common Name (CN) CN=myapp → username myapp
distinguished_name Full Distinguished Name CN=myapp,O=MyOrg → username CN=myapp,O=MyOrg
subject_alternative_name Subject Alternative Name (SAN) entry SAN dns:myapp.example.com → username myapp.example.com

When you use subject_alternative_name, you also configure ssl_cert_login_san_type (dns, ip, email, uri, or other_name) and ssl_cert_login_san_index to specify which SAN entry to use.

Note: The username extraction options for ssl_cert_login_from apply only to SSL certificate authentication. mTLS doesn’t extract identity from the client certificate.

Key configuration

The following rabbitmq.conf snippet shows the essential settings for SSL certificate authentication:

# Enable certificate-only authentication
auth_mechanisms.1 = EXTERNAL
ssl_cert_login_from = common_name
auth_backends.1 = internal
# Require client certificates
ssl_options.verify = verify_peer
ssl_options.fail_if_no_peer_cert = true
# AWS integration for certificate retrieval
aws.arns.assume_role_arn = ${AmazonMqAssumeRoleArn}
aws.arns.ssl_options.cacertfile = ${CaCertArn}

The following table describes what each setting controls:

Setting Purpose
auth_mechanisms.1 = EXTERNAL Enables the EXTERNAL SASL mechanism, authenticating clients using their X.509 certificate instead of a username and password
ssl_cert_login_from = common_name Tells the broker which certificate field to extract the username from
ssl_options.verify = verify_peer Enables client certificate verification
ssl_options.fail_if_no_peer_cert = true Rejects connections from clients that do not present a certificate
aws.arns.assume_role_arn IAM role ARN the broker assumes to retrieve certificates from ACM
aws.arns.ssl_options.cacertfile ARN of the CA certificate in ACM used to validate client certificates

Note: EXTERNAL and internal serve different purposes. EXTERNAL is the authentication mechanism that verifies client identity using the X.509 certificate. internal is the authorization backend that resolves permissions for the authenticated user from RabbitMQ’s built-in user store.

Important considerations

  1. Client certificates must be signed by a trusted Certificate Authority (CA). The broker validates the certificate chain during authentication.
  2. Amazon MQ enforces the use of AWS ARNs for certificate-related settings. Use aws.arns.ssl_options.cacertfile instead of ssl_options.cacertfile.
  3. Amazon MQ automatically creates a system user named monitoring-AWS-OWNED-DO-NOT-DELETE with monitoring-only permissions. This user uses RabbitMQ’s internal authentication system even on SSL certificate-enabled brokers and is restricted to loopback interface access only.
  4. If any setting requires the use of an AWS ARN, you must also provide aws.arns.assume_role_arn.
  5. Amazon MQ doesn’t currently support CRL or OCSP for certificate revocation. To revoke a client certificate that’s no longer trusted, replace the CA certificate on AWS Private Certificate Authority (AWS Private CA), re-issue valid client certificates, and apply a configuration update to the broker.
  6. To rotate certificates, update the CA certificate on AWS Private CA and update the broker configuration. Configuration changes don’t take effect immediately. To apply your changes, wait for the next maintenance window or reboot the broker.

How mutual TLS (mTLS) works

Standard TLS works like visiting a secure website: only the server proves its identity to your browser using a certificate. With mTLS, both your client application and the message broker must prove their identities using certificates. This two-way authentication helps verify that only authorized clients can connect to your broker. Unlike SSL certificate authentication, mTLS still requires a username and password at the application layer.

When your client connects to an Amazon MQ broker with mTLS enabled, the following authentication process occurs:

  1. The client initiates a TLS connection and presents its client certificate.
  2. The Amazon MQ broker assumes an IAM role to retrieve the CA certificate from ACM.
  3. The broker validates the client certificate against the CA certificate.
  4. The client authenticates with a username and password in the application layer.
  5. Authentication succeeds, and the broker establishes a secure, encrypted connection with the client.

Note: Unlike SSL certificate authentication, mTLS doesn’t extract the username from the certificate. The client certificate proves transport-layer trust only. The broker validates it against the CA certificate but does not use any certificate fields for application-level authentication. The username provided at login doesn’t need to match the client certificate’s CN.

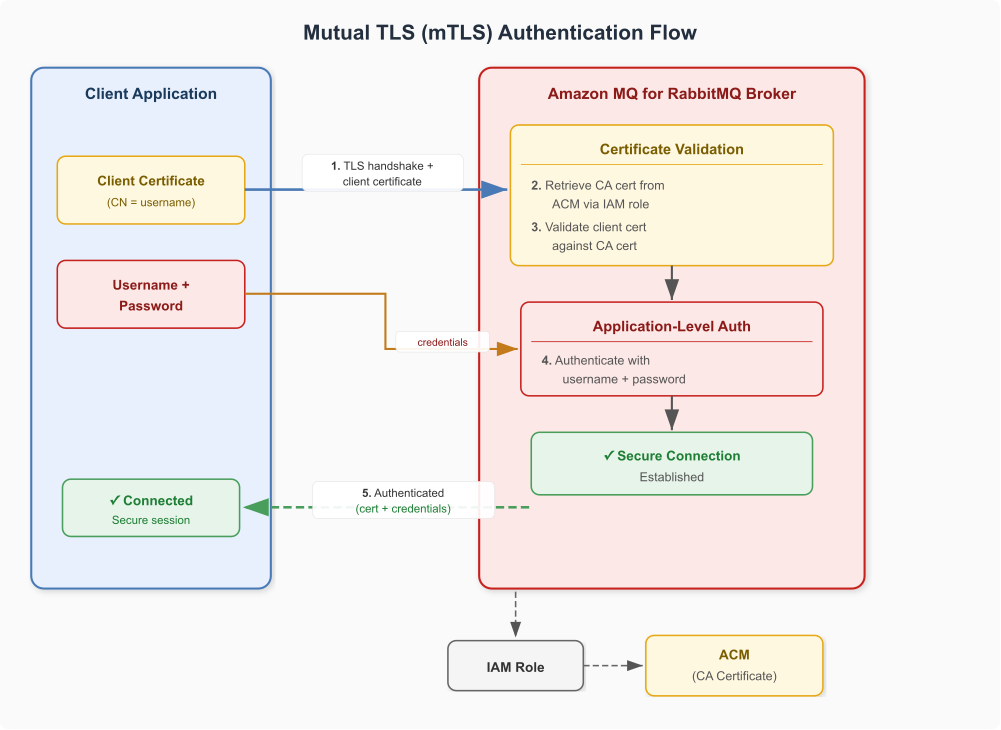
The following diagram illustrates this two-layer flow. On the left, the client application holds both a client certificate and a username and password. In the center, the arrows show the TLS handshake carrying the client certificate to the broker, followed by the credentials. On the right, the Amazon MQ for RabbitMQ broker performs certificate validation at the transport layer, assuming an IAM role to retrieve the CA certificate from ACM. It then authenticates the username and password at the application layer before establishing the secure connection to the client.

Mutual TLS flow in which the broker validates the client certificate, then authenticates the username and password at the application layer

Figure 2: Mutual TLS authentication flow

With mTLS, you can secure:

  • Client connections to the AMQP endpoint.
  • The RabbitMQ management interface.
  • Connections to OAuth 2.0 identity providers.
  • HTTPS authentication server connections.
  • Lightweight Directory Access Protocol (LDAP) server communications.

Key configuration

The following rabbitmq.conf snippet shows the essential settings for mTLS:

auth_backends.1 = internal
# Require client certificates for AMQP and management
ssl_options.verify = verify_peer
ssl_options.fail_if_no_peer_cert = true
management.ssl.verify = verify_peer
# AWS integration for certificate retrieval
aws.arns.assume_role_arn = ${AmazonMqAssumeRoleArn}
aws.arns.ssl_options.cacertfile = ${CaCertArn}
aws.arns.management.ssl.cacertfile = ${CaCertArn}

The following table describes the mTLS-specific settings and their purpose:

Setting Purpose
ssl_options.verify = verify_peer Enables client certificate verification for AMQP connections
ssl_options.fail_if_no_peer_cert = true Rejects connections from clients that do not present a certificate
management.ssl.verify = verify_peer Enables client certificate verification for the RabbitMQ management interface
aws.arns.ssl_options.cacertfile ARN of the CA certificate in ACM used to validate client certificates for AMQP
aws.arns.management.ssl.cacertfile ARN of the CA certificate in ACM used to validate client certificates for the management interface

Certificate requirements

Both SSL certificate authentication and mTLS require three types of certificates:

  • Server certificate: Authenticates the broker to clients. Obtain from AWS Private Certificate Authority (AWS Private CA) and reference using an AWS ARN.
  • Client certificates: Authenticate each client application to the broker. Issue from your organization’s CA or AWS Private CA.
  • CA certificate: Validates client certificates on the broker side. Store in ACM and reference in the broker’s SSL configuration.

Comparing SSL certificate authentication and mTLS

Use the following table to decide which method fits your security requirements:

Aspect SSL certificate authentication Mutual TLS (mTLS)
Authentication mechanism EXTERNAL SASL — certificate is the sole credential Transport-layer cert verification + username/password at application layer
Password required No Yes
Username source Extracted from certificate (CN, DN, or SAN) Provided by client at login
SASL mechanism EXTERNAL PLAIN (default)
Management interface cert verification Not included by default Supported through management.ssl.verify
Key config directive auth_mechanisms.1 = EXTERNAL ssl_options.verify = verify_peer
Use case Passwordless environments, PKI-managed identities Adding cert verification to existing credential-based auth
Compliance fit Environments requiring no passwords on the wire Frameworks requiring two-factor (something you have + something you know)

Choose SSL certificate authentication when eliminating passwords entirely from your messaging layer, or when your PKI infrastructure already manages client identities. Choose mTLS when adding transport-layer certificate verification to an existing deployment that relies on username/password authentication, or when compliance frameworks mandate two-factor authentication.

Additional SSL options

Both methods support the following additional configuration options:

Configuration Description
ssl_options.depth Maximum certificate chain depth for verification
ssl_options.hostname_verification Hostname verification mode: wildcard or none
ssl_cert_login_san_type SAN type when using Subject Alternative Name: dns, ip, email, uri, or other_name
ssl_cert_login_san_index Zero-based index of the SAN entry to use

Implementation guides

For step-by-step deployment and validation instructions, see the following resources:

Both tutorials use AWS CDK for infrastructure deployment and include validation scripts to test connectivity.

Conclusion

SSL certificate authentication and mTLS each address different security requirements for Amazon MQ for RabbitMQ. SSL certificate authentication uses the X.509 certificate as the sole credential through the EXTERNAL SASL mechanism, eliminating passwords entirely. mTLS adds transport-layer certificate verification on top of existing username/password authentication, giving you two-factor security. If you are building a regulated environment, SSL certificate authentication removes passwords from the wire entirely, which might help support security requirements in frameworks that address credential management. If you’re incrementally hardening an existing deployment, mTLS lets you add transport-layer verification without changing how clients authenticate. In the next post in this series, we cover OAuth 2.0, LDAP, and HTTP authentication for Amazon MQ for RabbitMQ.

To get started with Amazon MQ for RabbitMQ, see the Amazon MQ service page.

Additional resources

For more information about Amazon MQ security, see the following resources:


About the authors

Harshith Mithamar

Harshith Mithamar

Harshith is a Technical Account Manager at AWS. He works with enterprise customers to help them build secure, scalable messaging solutions on AWS.

Vinodh Kannan Sadayamuthu

Vinodh Kannan Sadayamuthu

Vinodh Kannan is a Senior Specialist Solutions Architect at Amazon Web Services (AWS). His expertise centers on AWS messaging and streaming services, where he provides architectural best practices consultation to AWS customers.

Authentication and authorization options for Amazon MQ for RabbitMQ

Post Syndicated from Vinodh Kannan Sadayamuthu original https://aws.amazon.com/blogs/big-data/authentication-and-authorization-options-for-amazon-mq-for-rabbitmq/

Managing authentication for message brokers at scale is complex: credentials sprawl, audit requirements, and integration with existing identity providers create operational overhead. The default approach of creating RabbitMQ users with static usernames and passwords works for getting started, but it quickly becomes a liability at scale. Credentials must be distributed securely, rotated regularly, and revoked promptly when team members change roles or leave the organization. For regulated industries, auditors want to see that your messaging infrastructure enforces the same identity and access controls as the rest of your environment.

Different organizations have different identity infrastructures. Some manage users through Active Directory. Others have standardized on OAuth 2.0. Platform teams building on AWS want to use AWS Identity and Access Management (IAM) roles and policies they understand. Security-conscious environments might require certificate-based authentication where no passwords are transmitted over the network at all.

Amazon MQ for RabbitMQ supports multiple authentication and authorization methods, so you can connect your broker to the identity infrastructure you already use. This post introduces the available options and helps you choose the right one for your use case.

Authentication methods at a glance

Amazon MQ for RabbitMQ supports the following authentication and authorization methods:

Method Credential type User management Recommended for
Simple credentials Username / password Broker-local Getting started, development environments
OAuth 2.0 Bearer tokens from external identity provider External identity provider Workloads that need short-lived tokens from a third-party identity provider
IAM authentication Short-lived JSON Web Tokens (JWTs) from AWS Security Token Service (AWS STS) IAM AWS-native workloads, multi-tenant isolation, credential-free authentication
LDAP Directory credentials Active Directory or LDAP server Organizations with existing directory services
HTTP-based auth backend Username / password validated by external server External HTTP server Custom auth logic, centralized user management across brokers
SSL certificate authentication Certificate only (passwordless) Broker-local (username extracted from cert) Eliminating passwords entirely with certificate-only identity
Mutual TLS (mTLS) Certificate and username/password Broker-local Adding transport-layer certificate verification to existing credential-based auth

Choosing the right method

The right choice depends on your existing identity infrastructure, security requirements, and operational preferences.

Simple credentials

The default method. You create RabbitMQ users with usernames and passwords directly on the broker. This is a straightforward way to get started, but it requires you to manage credentials manually. Choose this for development, testing, or small-scale deployments where credential management overhead is acceptable.

OAuth 2.0

Clients obtain short-lived tokens from any OAuth 2.0-compatible identity provider and present them to the broker as bearer tokens. Choose this when you have an existing identity provider (other than IAM) that issues tokens for your applications, and you want automatic token expiration without managing broker-local credentials.

IAM authentication

IAM serves as an identity provider. Client applications use their IAM credentials to obtain a short-lived JWT from AWS Security Token Service (AWS STS) and present it as a bearer token. IAM policies control which roles can obtain tokens. RabbitMQ scope aliases on the broker map each role’s Amazon Resource Name (ARN) to specific resource permissions (read, write, configure, and administrator). AWS CloudTrail logs every token issuance for auditing. Choose this when your workloads run on AWS compute services with IAM roles, and you want credential-free, IAM-native authentication with broker-level authorization.

LDAP

Connect your broker to an existing directory service such as Active Directory. Users authenticate with their directory credentials, and RabbitMQ permissions map to LDAP group memberships. Choose this when your organization already manages users and groups through a directory service, and you want to apply existing password policies and group-based access control to broker access.

HTTP-based auth backend

Delegates authentication and authorization decisions to a custom HTTPS server. The broker sends HTTP requests to your server for user validation, virtual host access, resource permissions, and topic permissions. Choose this when you need custom authentication logic, want to centralize user management across multiple brokers, or need to integrate with an identity system that doesn’t support OAuth 2.0 or LDAP natively.

SSL certificate authentication

Removes passwords entirely. The broker uses the EXTERNAL Simple Authentication and Security Layer (SASL) mechanism to extract the client’s identity directly from the X.509 certificate (for example, from the Common Name field) and uses it as the RabbitMQ username. With this method, your application doesn’t transmit credentials over the network. Choose this when your security policy requires passwordless authentication, and you manage client identities through a public key infrastructure (PKI).

Mutual TLS (mTLS)

Adds certificate verification on top of existing username/password authentication. During the TLS handshake, the client validates the broker’s certificate and the broker validates the client’s certificate, then the client provides a username and password at the application layer. This gives you two-factor security: something you have (the certificate) plus something you know (the password). Choose this when compliance frameworks require mutual authentication, but you want to retain your existing username/password authentication flow.

Conclusion

Amazon MQ for RabbitMQ version 4 supports seven authentication and authorization methods. With these methods, you can align your message broker security with your existing identity infrastructure. Your organization might standardize on IAM, manage identities through Active Directory, federate access through a third-party identity providers like Okta or Microsoft Entra ID, or rely on PKI for certificate-based trust. In each case, you can eliminate the operational overhead of managing static credentials at scale.

Choose your implementation path:

For sample code and infrastructure templates, clone the
Amazon MQ samples repository and deploy the CDK stack for your chosen authentication method.

About the authors

Vinodh Kannan Sadayamuthu

Vinodh Kannan Sadayamuthu

Vinodh is a Senior Specialist Solutions Architect at Amazon Web Services (AWS). His expertise centers on AWS messaging and streaming services, where he provides architectural best practices consultation to AWS customers.

Vignesh Selvam

Vignesh Selvam

Vignesh is the Principal Product Manager for Amazon MQ at AWS. He works with customers to solve their messaging needs and with the open-source communities for innovating with message brokers. Prior to joining AWS, he built products for security and analytics.

Introducing public preview runtimes on AWS Lambda, starting with Node.js 26 and Python 3.15

Post Syndicated from Jonathan Tuliani original https://aws.amazon.com/blogs/compute/introducing-public-preview-runtimes-on-aws-lambda-starting-with-node-js-26-and-python-3-15/

Today, AWS Lambda introduces public preview runtimes, a new way to try upcoming language versions on Lambda before their general availability (GA) release. Starting today, you can create and update Lambda functions using Node.js 26 and Python 3.15, the first runtimes available as public previews.

Previously, Lambda has always launched new runtimes as Generally Available (GA), giving you a production-ready experience from day one. But this means you couldn’t run your functions on Lambda using a pre-release language version, and we couldn’t hear your feedback while breaking changes were still possible. Public preview runtimes change that. By putting pre-GA runtimes in your hands months earlier, we can listen to your feedback and address it before GA, while we still have the opportunity to make breaking changes to improve the runtime.

Preview runtimes are available in all AWS commercial Regions, AWS GovCloud (US) Regions, and China Regions. They use the same runtime identifier as the eventual GA runtime, so your functions graduate automatically when the runtime reaches GA, with no action required.

Why public preview runtimes

When Lambda launches a new runtime as GA, that means it is ready for use in production workloads from day one. Historically, the Lambda team has validated new runtimes through internal testing and pre-release benchmarking. However, without real customer workloads running on the runtime, some issues only surface after the GA launch. And once the runtime is GA, the scope to address those issues is much reduced since we cannot risk breaking existing production workloads.

Public preview runtimes address this by opening up a pre-GA feedback window. During this period, you can deploy functions using the upcoming runtime, and the Lambda team can act on what you find, including making potentially breaking changes if necessary. In addition, because the upstream language is still in its pre-release phase, there’s also the opportunity that issues discovered during preview can be fixed in the runtime itself, not just worked around.

This benefits everyone involved. You get a runtime that’s been tested against a broader range of real workloads before it reaches GA. Third-party partners, including observability providers, infrastructure-as-code tools, and deployment frameworks, get time to validate compatibility. And upstream language communities get a signal from a major cloud platform while they can still act on it.

This is the first time we’re launching runtimes as public previews. As such, it’s an experiment. We hope to make public previews the default for all future runtime launches, depending on the success of this experiment and the feedback we receive.

What’s included in the preview runtimes

The Node.js 26 and Python 3.15 preview runtimes are built on the latest upstream pre-release of each language version. At launch, they are a straightforward version bump. There are no additional Lambda-specific enhancements beyond what the new language version itself provides. For details on what’s new in each language version, refer to the upstream release information:

Preview runtimes are available as both managed runtimes and base container images. The base images are published to the Lambda base image ECR repository with image tags starting with 3.15-preview (for Python) and 26-preview (for Node.js).

During the preview period, we may introduce additional features or enhancements to these runtimes. When we do, we’ll announce them on the same GitHub issue we use to collect your feedback:

Follow these issues to stay informed of any changes during the preview period.

What to expect during preview

Preview runtimes follow the same patching cadence as GA runtimes. When an update is released upstream, Lambda applies it to the preview runtime on the same schedule as any other supported runtime. All Lambda features supported by the current GA runtimes are available on the preview runtimes, including Lambda Managed Instances and durable functions.

The key difference is that the underlying language version has not yet reached its stable release. In addition, the Lambda team is still working on the runtimes to add features and optimize performance. This means breaking changes may occur during the preview period. A function that works today may require a fix after Lambda rolls out the next runtime update. This is by design: the preview period exists so that these issues can be found and resolved before GA, not after.

Because of this potential for breaking changes, preview runtimes are not covered by the AWS Lambda SLA or AWS technical support plans. We strongly recommend against using them for production workloads. Lambda emits a warning message to CloudWatch Logs on each cold start to make it clear when a function is running on a preview runtime:

WARNING: This is a preview runtime version and should not be used for production workloads. For further information and to provide feedback, see https://docs.aws.amazon.com/lambda/latest/dg/lambda-runtimes.html.

You may notice that, at launch, preview runtimes have slower performance than GA runtimes, in particular for cold starts. This is because of a combination of lack of optimization and less caching in internal Lambda sub-systems. We will benchmark and optimize performance during the preview period, prior to GA.

Functions that use preview runtimes are billed at standard Lambda rates. There is no additional cost or separate pricing.

Share your feedback

We want to hear from you during the preview period. We’ve created a dedicated GitHub issue for each preview runtime where you can share your experience:

Comment on these issues directly, or open a separate issue in the repository if you prefer.

We’re interested in all feedback, not just bug reports. If you see an opportunity to take advantage of a new language feature in the runtime, or a way to improve the Lambda programming model for that language, we want to hear about it. The preview period is when we can still make meaningful changes, so this is the best time to share your ideas.

Note that feedback should be scoped to the runtime itself: the execution environment, language integration, and programming model. For broader Lambda feature requests, refer to the AWS Lambda public roadmap.

Transition to GA

Both Node.js 26 and Python 3.15 are expected to reach their stable upstream releases in October 2026. Lambda GA for each runtime is targeted within two months following those releases. For the latest estimated GA dates, see Lambda documentation.

For Node.js, the GA timeline is tied to the Node.js “Active LTS” release, which is scheduled for October 2026. Only at that point is the release considered suitable for production workloads by the Node.js project, and only then is it sufficiently stable for Lambda’s automatic runtime patching in which patches are applied to your functions without action on your part. Lambda will not GA the Node.js 26 runtime until it reaches Active LTS.

When a preview runtime reaches GA, your functions graduate automatically. The runtime identifier does not change: nodejs26.x in preview is the same nodejs26.x at GA. You do not need to update your function configuration, templates, or code. The preview label is removed from the console and documentation, the runtime becomes covered by the Lambda SLA and AWS Support, and the GA performance and quality bar applies from that point forward.

If you have pinned your function to a specific runtime version using Runtime Management Controls during the preview period, it remains pinned. You can unpin at any time to move to the GA runtime. Functions pinned to a pre-GA runtime version are not covered by the Lambda SLA and AWS Support.

Getting started

You can start using the Node.js 26 and Python 3.15 preview runtimes today using the Lambda console, AWS Command Line Interface (AWS CLI), AWS CloudFormation, AWS Serverless Application Model (AWS SAM), or AWS Cloud Development Kit (AWS CDK).

Console

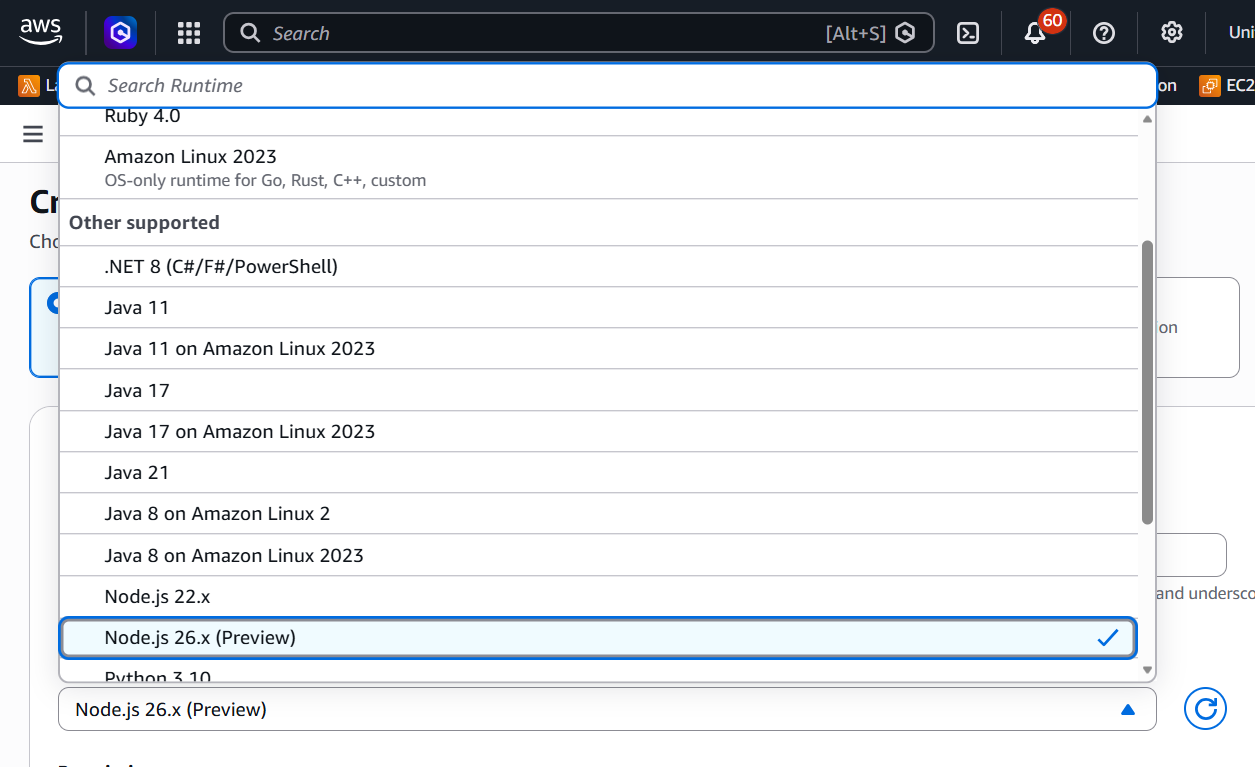
In the Lambda console, choose “Node.js 26 (Preview)” or “Python 3.15 (Preview)” from the runtime list when creating or updating a function.

Screenshot of the Lambda console runtime list showing “Node.js 26 (Preview)” and “Python 3.15 (Preview)” options.

AWS CLI

Create a function using the preview runtime with the standard runtime identifier:

aws lambda create-function \
  --function-name my-function \
  --runtime nodejs26.x \
  --handler index.handler \
  --role arn:aws:iam::123456789012:role/my-role \
  --zip-file fileb://function.zip

For Python 3.15, use --runtime python3.15. These are the same identifiers the GA runtimes will use, there is no separate preview-specific value.

AWS CloudFormation

Specify the preview runtime in your CloudFormation template using the same runtime identifier:

Resources:
  MyFunction:
    Type: AWS::Lambda::Function
    Properties:
      FunctionName: my-function
      Runtime: nodejs26.x
      Handler: index.handler
      Role: arn:aws:iam::123456789012:role/my-role
      Code:
        S3Bucket: amzn-s3-demo-function-code
        S3Key: function.zip

AWS SAM

AWS SAM supports preview runtimes using the standard runtime identifier in your template:

Resources:
  MyFunction:
    Type: AWS::Serverless::Function
    Properties:
      Runtime: python3.15
      Handler: app.lambda_handler
      CodeUri: src/

When you run sam init, preview runtimes appear in the template list with a “(Preview)” label, so you can scaffold a new project directly.

AWS CDK

The AWS CDK does not yet include built-in enum members (such as Runtime.NODEJS_26_X). During the preview phase, you can use the public Runtime constructor to specify the runtime directly, for example:

import { Stack, StackProps } from "aws-cdk-lib";
import { Construct } from "constructs";
import { Function, Runtime, RuntimeFamily, Code } from "aws-cdk-lib/aws-lambda";

export class LambdaStack extends Stack {
  constructor(scope: Construct, id: string, props?: StackProps) {
    super(scope, id, props);

    new Function(this, "MyFunction", {
      runtime: new Runtime("nodejs26.x", RuntimeFamily.NODEJS),
      handler: "index.handler",
      code: Code.fromAsset("lambda"),
    });
  }
}

Or, for Python 3.15, replace new Runtime("nodejs26.x", RuntimeFamily.NODEJS) with new Runtime("python3.15", RuntimeFamily.PYTHON).

This synthesizes identical CloudFormation to what a built-in enum produces. When the runtime reaches GA, a corresponding enum member will be added. There is no functional difference in the meantime.

Conclusion

Public preview runtimes give you a seat at the table while Lambda’s next runtimes are still taking shape. Try using Node.js 26 or Python 3.15 today to deploy a function, run your test suite, and let us know what you find.

Share feedback and follow along:

These GitHub issues are where we’ll post any enhancements or breaking changes during the preview period, so they’re worth watching even if you don’t have immediate feedback. The preview runtimes are available today in all AWS Regions, including AWS GovCloud (US), and the AWS China Regions. To learn more, see the Lambda runtimes documentation.

AWS Certificate Manager will discontinue email validation to prove domain validation for certificates

Post Syndicated from Adam Aboudi original https://aws.amazon.com/blogs/security/aws-certificate-manager-will-discontinue-email-validation-to-prove-domain-validation-for-certificates/

Today, we’re announcing that AWS Certificate Manager (ACM) will discontinue support for email-validated public certificates by September 30, 2027. If you use email validation for your ACM public certificates, you need to migrate to DNS validation before that date. This change aligns with the Certification Authority/Browser (CA/B) Forum’s industry-wide deprecation of email-based domain validation and gives you a full year to migrate ahead of the Forum’s March 2028 deadline.

In this blog post, we share the rationale for this change, the timeline, and the steps you can take to migrate your certificates to DNS validation.

Background

The CA/B Forum sets the standards that browsers and certificate authorities must follow for publicly trusted certificates. In November 2025, they voted to end support for email-based domain validation effective March 15, 2028. After that date, certificates validated through email won’t be trusted by browsers, regardless of which certificate authority issued them.

ACM will be deprecating its email validation in-line with the CA/B Forum’s requirements, by September 30, 2027. The ACM timeline gives customers one year to migrate before the CA/B Forum’s hard deadline.

Timelines for these changes

If you currently use email validation for certificates requested from ACM, there are a few important dates that you should be aware of:

  • January 1, 2027: ACM will no longer offer email validation in new AWS Regions.
  • March 31, 2027: ACM will no longer offer email validation for new certificate requests in any Region.
  • September 30, 2027: ACM will no longer renew existing certificates that use email validation in any Region.
  • March 15, 2028: Per the CA/B Forum, public certificate authorities can no longer use email-based domain validation to issue or renew publicly trusted certificates. Certificates issued before this date remain valid until they expire.

Check for existing email validated certificates

If you have any ACM issued public certificates, you can check whether any of them are email validated by using the AWS Management Console for ACM or the AWS Command Line Interface (AWS CLI).

Identify email validated certificates using the ACM console

Use the following steps in the console to find email validated certificates.

  1. Open the ACM console.
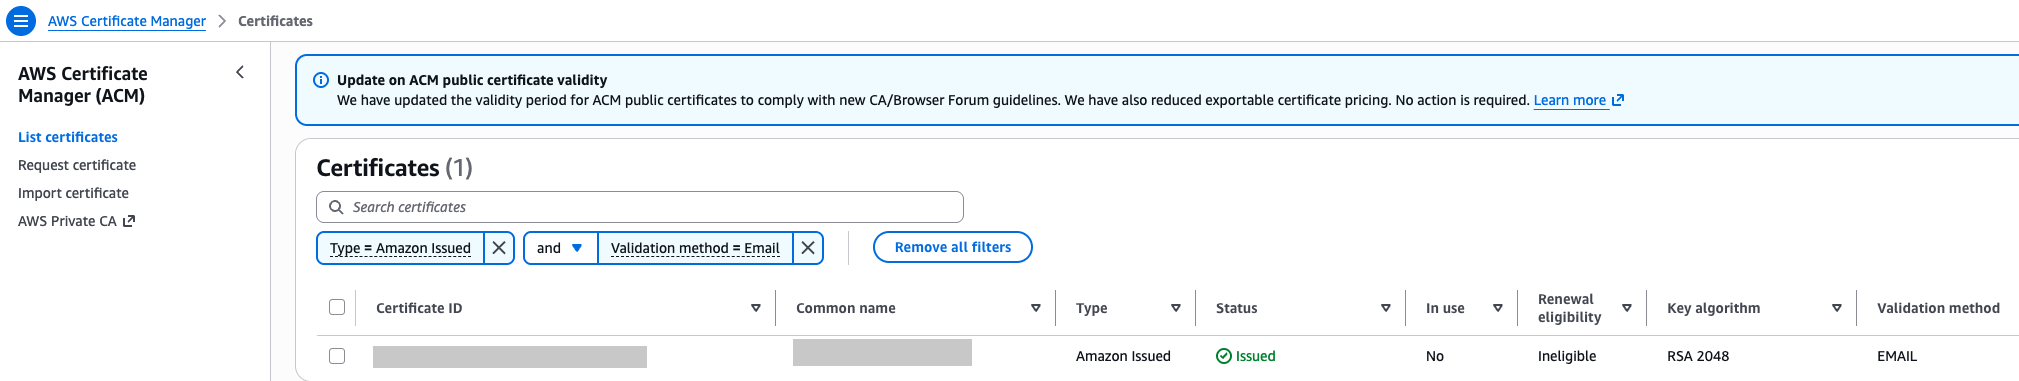
  2. Select the filters Validation method = Email and Type = Amazon Issued for a list of email validated certificates.
  3. Any certificates listed are public email-validated certificates and should be migrated before September 30, 2027.
  4. Figure 1: List of all public email validated certificates

    Figure 1: List of all public email validated certificates

Identify email-validated certificates using the AWS CLI

Use the following commands to find email validated certificates.

# Discover email validated public certificates 
region="${1:-us-east-1}" 

aws acm list-certificates --region "$region" \ 
--query "CertificateSummaryList[?Type=='AMAZON_ISSUED'].CertificateArn" --output text | tr '\t' '\n' | while read -r arn; do aws acm describe-certificate --region "$region" --certificate-arn "$arn" \
--query 'Certificate.[DomainName,Type,DomainValidationOptions[0].ValidationMethod]' \ 
--output text done | awk -F'\t' '$3 == "EMAIL"' | column -t 

Usage: 
chmod +x list-email-validated-certs.sh 
./list-email-validated-certs.sh # default region, us-east-1 
./list-email-validated-certs.sh us-west-2 # another region

Migrate existing email validated certificates

To assist you in this migration, ACM is updating the UpdateCertificateOptions API so you can switch a certificate’s validation method from email to DNS in place. This means the certificate Amazon Resource Name(ARN) will remain the same and no changes will be needed to your AWS resources that reference the certificate.

When you update a certificate to DNS validation, ACM provides a CNAME record to add to your DNS configuration, and you have 72 hours to add that record. During this window, the certificate continues to function normally on email validation. If the 72 hours elapse without a DNS update, the certificate stays active on email validation and you can retry when ready. After DNS validation is complete, ACM is designed to automatically renew your certificate before it expires without further manual intervention required. We recommend completing migration before September 30, 2027, so that ACM can keep your certificates up to date without interruption.

To migrate using the console

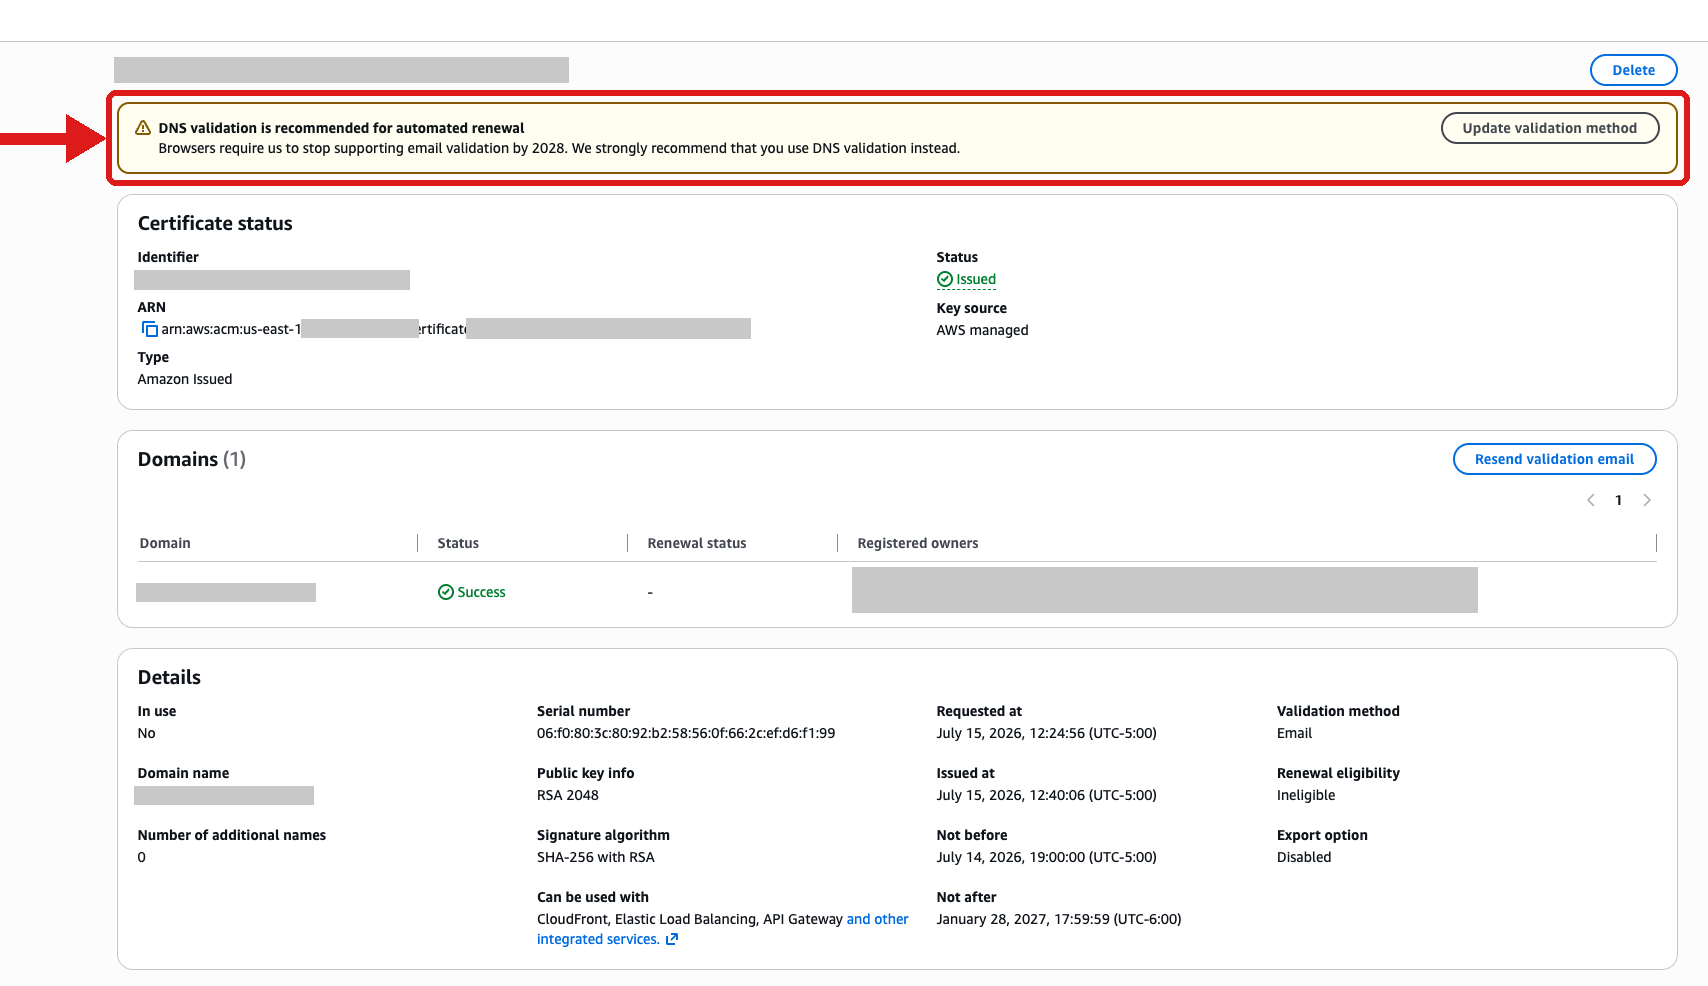
  1. After you’ve identified a certificate that needs updating, open it and select Update validation method at the top of the page.
    Figure 2: DNS Validation prompt when viewing an email validated public certificate.

    Figure 2: DNS Validation prompt when viewing an email validated public certificate.

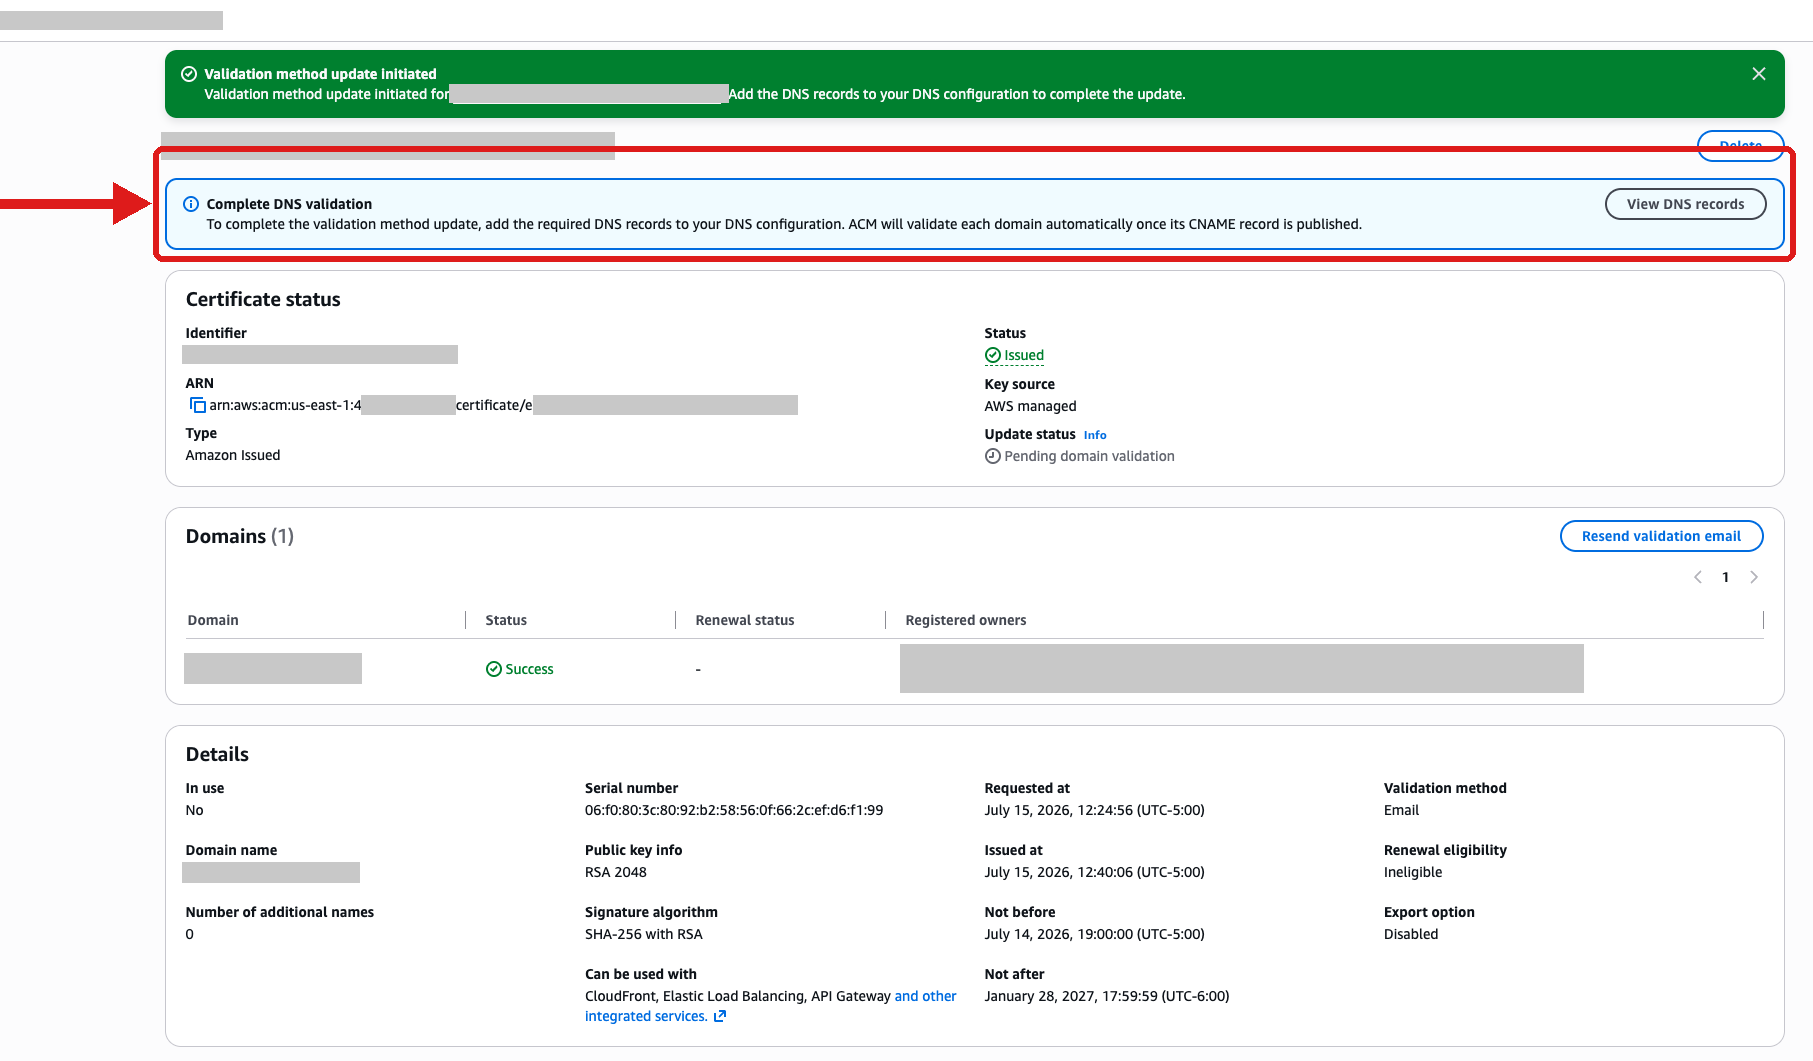
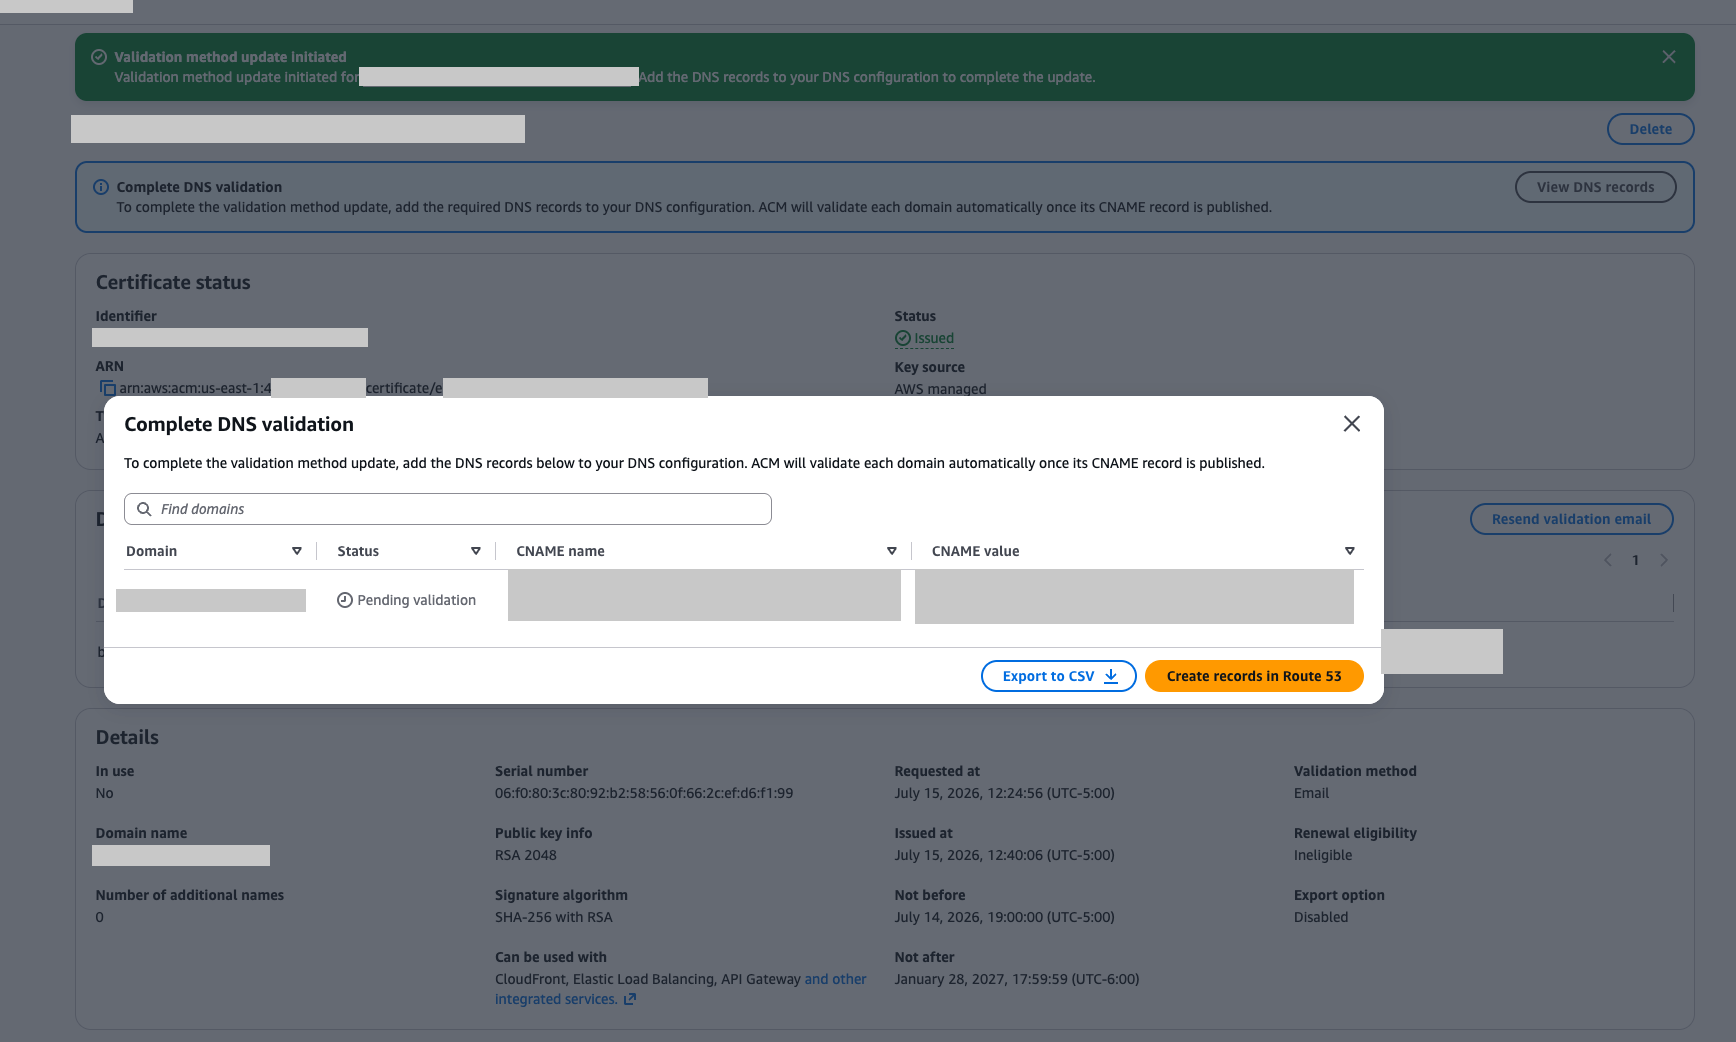
  2. After the update is triggered, you will see a View DNS records flashbar at the top of the certificate page.
    Figure 3: View DNS validation records after updating validation method.

    Figure 3: View DNS validation records after updating validation method.

  3. Select View DNS Records in the flashbar to open a dialog box from which you can download the CSV file for the CNAME records to export to other DNS providers.
    Figure 4: Get DNS validation information from the dialog box

    Figure 4: Get DNS validation information from the dialog box

  4. For Route 53 users, there is a Create records in Route 53 that makes the validation available as a one-click option.
    Figure 5: Create DNS validation records into Route 53

    Figure 5: Create DNS validation records into Route 53

To migrate using the AWS CLI:

For instructions on how to update certificates using the AWS CLI, see the email to DNS migration user guide.

Alternatives after email validation is no longer available

ACM supports two validation methods for new certificates going forward:

  • DNS validation – Add a CNAME record to your DNS configuration. ACM automatically renews DNS-validated certificates as long as the record remains in place. We recommend this method for most use cases.
  • HTTP validation for CloudFront – ACM provides a unique token that you host at a well-known URL path on your domain. This method is only available for certificates used with Amazon CloudFront.

Both methods remove the manual approval step required by email validation and let ACM renew your certificates automatically.

Conclusion

The deprecation of email validation and use of the new UpdateCertificateOptions API helps keep your certificates trusted and your applications running as industry standards evolve. The updated UpdateCertificateOptions API is designed to make this migration straightforward: switch your validation method in place, add the DNS record, and ACM is designed to handle renewals automatically from that point forward.

If you have questions or need assistance migrating, contact AWS Support or start a new thread on the AWS re:Post ACM Forum.

If you have feedback about this post, submit comments in the Comments section below.


Adam Aboudi

Adam Aboudi

Adam is a Senior Technical Product Manager on the AWS Certificate Manager team. He focuses on helping customers simplify certificate lifecycle management and maintain strong security posture across their AWS environments.

Poojil Tripathi

Poojil Tripathi

Poojil is a Solutions Architect at AWS based out of Austin, TX. They work with AWS customers to help them design secure architectures for all types of workloads. They would like to remind you to dance like no one is watching, but encrypt like everyone is.

Landing Zone Accelerator Independent Assessment Report for C5:2020 now available on AWS Artifact

Post Syndicated from Kevin Donohue original https://aws.amazon.com/blogs/security/landing-zone-accelerator-independent-assessment-report-for-c52020-now-available-on-aws-artifact/

Organizations operating in Germany and across Europe increasingly need to demonstrate cloud security compliance under the Cloud Computing Compliance Criteria Catalogue (C5:2020), published by Germany’s Federal Office for Information Security (BSI). Last year, we introduced Landing Zone Accelerator on AWS support for digital sovereignty and today we’re announcing the availability of a new independent assessment report available on AWS Artifact which evaluates how the Landing Zone Accelerator (LZA) on AWS solution provides enhanced coverage for C5:2020 requirements by implementing nearly 200 native security controls. LZA is available using a standard multi-account configuration or as a container-based deployment option in the AWS European Sovereign Cloud, enabling customers with data residency requirements to use the same security configuration baseline.

How this accelerates your compliance journey

Security and compliance are a shared responsibility. LZA takes on part of this responsibility by defining a security architecture baseline and automatically provisioning your AWS environment that scales as your organization grows. Where AWS already provides C5 Type 2 attestation reports for “security of the cloud”, the LZA assessment report offers an independent opinion of how the security baseline LZA provisions aligns with C5:2020 criteria for “security in the cloud”. Instead of starting from scratch, you can deploy with LZA, evaluate the scope of coverage from the report, and use the LZA Compliance Workbook to build on and customize for your organization’s unique use case. These resources can help you reduce time in architecture design, evidence collection, and preparation for C5:2020 assessments. The free LZA Compliance Workbook available on AWS Artifact and open source Universal Configuration GitHub repository are also excellent sources to add to a knowledge base, enabling you to create a security compliance chat agent with Bedrock to assist your governance or assurance teams.

What’s in the report

AWS Partner Schellman, an independent third-party assessor, evaluated the LZA Universal Configuration architecture and security control baseline, which maps to C5:2020 controls in the LZA Compliance Workbook, to determine how the LZA infrastructure aligns to C5:2020 technical requirements. The report concluded that LZA can help implement 325 security controls in aggregate, aligning to technical requirements from eight C5:2020 control areas. It also describes the LZA architecture design, security best practices, and scoping considerations for C5:2020 assessments. This is the first installation of the independent C5 report for LZA, which will be updated in 2027 to evaluate coverage for the pending C5:2026 revision.

In addition to the LZA C5:2020 report, you can also find the LZA Compliance Workbook available on AWS Artifact. It maps C5:2020 requirement identifiers to security implementation statements, giving you a starting point from which you can customize and enhance your compliance documentation for your unique workloads or operational practices after deploying LZA.

Getting started with LZA for C5

  1. Sign in to your AWS account first and then download the LZA C5:2020 Independent Assessment Report and LZA Compliance Workbook from AWS Artifact.
  2. Visit the LZA Universal Configuration GitHub repository to review and download the latest configuration baseline. Also, see guidance for European Sovereign Cloud LZA deployments.
  3. The LZA Implementation Guide walks you through deployment steps, use cases, and pre-deployment considerations.

To learn more, submit a question to a LZA team member or contact your AWS account representative.

If you have feedback about this post, submit comments in the Comments section below.


Kevin Donohue

Kevin Donohue

Kevin is a Senior Security Compliance Engineer at AWS, where he builds solutions and resources to help AWS customers achieve their security and compliance goals. Prior to joining the Landing Zone Accelerator team in AWS Professional Services in 2024, Kevin began his tenure with AWS Security in 2019 specializing in FedRAMP compliance and the shared responsibility model.

Michael Wahlers

Michael Wahlers

Michael is a Principal Solutions Architect and Public Sector Specialist working across Germany, Austria, and Switzerland. With passionate enthusiasm, he supports public institutions with innovative digital solutions. His expertise ensures seamless service delivery, making him a valuable asset in shaping the digital future of the public sector. He also enjoys exploring complex distributed systems and incorporating local contexts into his work.

Summer 2026 SOC 1 report is now available with 185 services in scope

Post Syndicated from Baj Bajwa original https://aws.amazon.com/blogs/security/summer-2026-soc-1-report-is-now-available-with-185-services-in-scope/

Amazon Web Services (AWS) is pleased to announce that the Summer 2026 System and Organization Controls (SOC) 1 report is now available. The reports cover 185 services over the 12-month period from July 1, 2025–June 30, 2026, giving customers a full year of assurance. These reports demonstrate our continuous commitment to adhering to the heightened expectations of cloud service providers.

Customers can download the Summer 2026 SOC 1 report through AWS Artifact, a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

AWS strives to continuously bring services into the scope of its compliance programs to help customers meet their architectural and regulatory needs. You can view the current list of services in scope on our Services in Scope page. As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback about SOC compliance.

To learn more about AWS compliance and security programs, see AWS Compliance Programs.


Baj Bajwa

Baj Bajwa

Baj is a Security Assurance Manager at AWS, where he leads the Global Third-Party Assurance product portfolio within the Compliance and Security Assurance (CSA) organization. He has over 15 years of experience in information security, compliance, and risk management, and holds a master’s degree in cybersecurity. Baj maintains CISSP, CISA, PMP, CCSK, GISF, and ICAgile certifications.

Tushar Jain

Tushar Jain
Tushar is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives Tushar holds a Master of Business Administration from Indian Institute of Management Shillong, India and a Bachelor of Technology in electronics and telecommunication engineering from Marathwada University, India. He has over 14 years of experience in information security and holds CISM, CCSK and CSXF certifications.

Michael Murphy

Michael Murphy
Michael is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives. Michael has over 14 years of experience in information security and holds a master’s degree and a bachelor’s degree in computer engineering from Stevens Institute of Technology. He also holds CISSP, CRISC, CISA, and CISM certifications.

Jeff Cheung

Jeff Cheung
Jeff is a Compliance Program Manager at AWS where he leads multiple security and privacy initiatives across business lines. Jeff has Bachelors degrees in Information Systems, and Economics from SUNY Stony Brook, and has over 20 years of experience in information security and assurance. Jeff has held professional certifications such as CISA, CISM, and PCI-QSA.

Logan Moore

Logan Moore
Logan is a Compliance Program Manager at AWS where he leads multiple security and compliance initiatives. Logan has over 10 years of experience in information security and holds a Bachelor’s Degree in Information Systems Management from Virginia Polytechnic Institute and State University.

Noah Miller

Noah Miller
Noah is a Compliance Program Manager at AWS and leads multiple security and privacy initiatives. Noah has 7 years of experience in information security. He has a master’s degree in Cybersecurity Risk Management and a bachelor’s degree in Informatics from Indiana University.

Will Black
Will Black

Will is a Compliance Program Manager at Amazon Web Services where he leads multiple security and compliance initiatives. Will has 10 years of experience in compliance and security assurance and holds a degree in Management Information Systems from Temple University. Additionally, he is a PCI Internal Security Assessor (ISA) for AWS and holds the CCSK and ISO 27001 Lead Implementer certifications.
Ziv Wand
Ziv Wand

Ziv is a Compliance Program Manager at AWS and leads multiple security and privacy initiatives. Ziv has over 6 years of experience in information security assurance, external IT security audits, security control design and implementation, and audit readiness. He holds a Bachelor of Science in Management Information Systems from Binghamton University.
Shalini Mishra
Shalini Mishra

Shalini is a Compliance Program Manager at AWS. She has over 5 years of experience leading end-to-end compliance programs across ISO, SOC, and cloud security frameworks, with deep expertise in third-party risk management and enterprise governance. Shalini holds a Master of Science degree in Information Systems and a CRISC certification.
Patrick Broussard

Patrick Broussard
Patrick is a Security Assurance Analyst at AWS, where he assists with multiple security and privacy initiatives, with expertise in physical security and infrastructure management. He has over 3 years of experience in information security assurance and infrastructure security control operation, and holds a Bachelors of Science from Virginia Polytechnic Institute and State University.

Jimmy Chang

Jimmy Chang
Jimmy is a Security Assurance Analyst at AWS, where he assists with multiple security and privacy initiatives, with expertise in application security and secure software development life cycle. He has over 4 years of experience in information security and holds CISSP and CCSK certifications, and holds a Master of Information Systems Management from Carnegie Mellon University.

Faraz Haq

Faraz Haq
Faraz is a Compliance Program Manager at AWS leading various compliance and security assurance initiatives. Faraz has over 10 years of experience in information security and compliance. He holds Bachelor of Science Degrees in Accounting and Finance from Oakland University.

AWS successfully completed its 2025-26 NHS DSPT assessment

Post Syndicated from Tariro Dongo original https://aws.amazon.com/blogs/security/aws-successfully-completed-its-2025-26-nhs-dspt-assessment/

Amazon Web Services (AWS) is pleased to announce its successful completion of the 2025-26 NHS Data Security and Protection Toolkit (NHS DSPT) assessment audit and achieving a status of Standards Exceeded.

The NHS DSPT is an assessment that allows organizations to measure their performance against the National Data Guardian’s 10 data security standards. All organizations that access NHS patient data and systems are expected to use the toolkit to demonstrate their compliance with safe data security standards. NHS DSPT covers standards regarding Personal Confidential Data, Continuity Planning, IT Protection, and more. AWS undergoes the assessment to provide customers with assurance that we are practicing good data security.

The AWS NHS DSPT assessment status is valid until June 30, 2027, and a certificate that confirms our compliance is available on the NHS England website and in AWS Artifact. AWS Artifact is a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.

Security and compliance is a shared responsibility between AWS and the customer. When customers move their computer systems and data to the cloud, security responsibilities are shared between the customer and the cloud service provider. For more information, see the AWS Shared Security Responsibility Model.

To learn more about our compliance and security programs, see AWS Compliance Programs.

As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback.

If you have feedback about this post, submit comments in the Comments section below.


Tari Dongo

Tariro Dongo

Tari is a Security Assurance Program Manager at AWS, based in London. She is responsible for third-party and customer audits, attestations, certifications, and assessments across EMEA. Tari has worked in security assurance and technology risk in the big four and financial services industry for over 15 years.

AWS completes the 2026 Police-Assured Secure Facilities (PASF) audit in Europe (London)

Post Syndicated from Tariro Dongo original https://aws.amazon.com/blogs/security/aws-completes-the-2026-police-assured-secure-facilities-pasf-audit-in-europe-london/

We’re excited to announce that our Europe (London) AWS Region has renewed its accreditation for United Kingdom (UK) Police-Assured Secure Facilities (PASF) for Official-Sensitive data. Since 2017, the Amazon Web Services (AWS) Europe (London) Region has been accredited under the PASF program. This demonstrates our continuous commitment to adhere to the heightened expectations of customers with UK law enforcement workloads. Our UK law enforcement customers who require PASF can continue to run their applications in the PASF-accredited Europe (London) Region in confidence.

The PASF is a long-established assurance process, used by UK law enforcement, as a method for assuring the security of facilities such as data centers or other locations that house critical business applications that process or hold police data. PASF consists of a control set of security requirements, an on-site inspection, and an audit interview with representatives of the facility.

The Police Digital Service (PDS) confirmed the accreditation renewal for AWS on May 28, 2026. A confirmation letter can be found on AWS Artifact. The UK police force and law enforcement organizations can also obtain confirmation of the compliance status of AWS through the Police Digital Service.

To learn more about our compliance and security programs, see AWS Compliance Programs.

As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback.

If you have feedback about this post, submit comments in the Comments section below.


Tari Dongo

Tariro Dongo

Tari is a Security Assurance Program Manager at AWS, based in London. She is responsible for third-party and customer audits, attestations, certifications, and assessments across EMEA. Tari has worked in security assurance and technology risk in the big four and financial services industry for over 15 years.

2026 AWS CyberVadis report now available for due diligence on third-party suppliers

Post Syndicated from Tariro Dongo original https://aws.amazon.com/blogs/security/2026-aws-cybervadis-report-now-available-for-due-diligence-on-third-party-suppliers/

We’re excited to announce that Amazon Web Services (AWS) has completed theCyberVadis assessment of its security posture with the highest score (Mature) in all assessed areas. This demonstrates our continued commitment to meet the heightened expectations for cloud service providers. Customers can now use the 2026 AWS CyberVadis report and scorecard to reduce their supplier due-diligence burden.

With the increasing adoption of cloud products and services across multiple sectors and industries, AWS is a critical component of customers’ third-party environments. Regulated customers, such as those in the financial services sector, are held to high standards by regulators and auditors when it comes to exercising effective due diligence on third parties.

Many customers use third-party risk management services such as CyberVadis to better manage risks from their evolving third-party environments and drive operational efficiencies. In support of these efforts, AWS has completed its annual CyberVadis security posture assessment, conducted by CyberVadis security analysts.

CyberVadis is a comprehensive third-party risk assessment process that combines the speed and scalability of automation with the certainty of analyst validation. CyberVadis assessments employ a dynamic and comprehensive approach to third-party risk assessment, replacing outdated static spreadsheets and the need for annual AWS assessment access requests. This cloud-based solution provides advanced capabilities by integrating AWS responses with analytics and sophisticated risk models to deliver an in-depth view of the security posture of AWS.

CyberVadis’s risk assessment methodology evaluates 20 topics covering the entire cybersecurity life cycle across four phases: Identify, Protect, Detect, and React. These topics include Data Privacy, Access Management, and Infrastructure Security. The assessment criteria are based on international information security standards, including ISO 2700x, NIST Cybersecurity Framework, Cybersecurity for ICS, PCI DSS, NIS2 and GDPR.

Customers can use CyberVadis results to map the assessment of AWS to commonly used industry frameworks and standards to instantly gain visibility into controls coverage.

AWS customers can download the complete 2026 AWS Assessment Report directly through CyberVadis’s portal using their own account, or through AWS Artifact.

To learn more about our other compliance and security programs, see AWS Compliance Programs.

As an AWS customer, you can reach out to your AWS account team if you have any questions or feedback.

If you have feedback about this post, submit comments in the Comments section below.


Tari Dongo

Tariro Dongo

Tari is a Security Assurance Program Manager at AWS, based in London. She is responsible for third-party and customer audits, attestations, certifications, and assessments across EMEA. Tari has worked in security assurance and technology risk in the big four and financial services industry for over 15 years.

Amazon OpenSearch Service extends version lifecycle support timelines

Post Syndicated from Kuldeep Yadav original https://aws.amazon.com/blogs/big-data/amazon-opensearch-service-extends-version-lifecycle-support-timelines/

In November 2024, we announced Standard and Extended Support dates for legacy Elasticsearch versions (1.5 through 7.8) and OpenSearch versions (1.0 through 1.2, and 2.3 through 2.9) running on Amazon OpenSearch Service. At that time, Extended Support for these versions was set to end on November 7, 2026 (except Elasticsearch 5.6, for which Extended Support ends on November 7, 2028), after which domains would no longer receive security fixes or operating system patches.

Since that announcement, many customers have upgraded to newer versions. However, some customers need more time to plan and complete their migrations. To provide this flexibility, we are continuing security and operating system patch coverage for these versions for an additional 12 months, through November 7, 2027, at an updated support rate.

Today, we’re announcing two updates: Extended Support extension for present versions and End of Standard Support and Extended Support for additional versions.

Extended Support extension for present versions

We are continuing security and operating system patch coverage for Elasticsearch versions 1.5 through 7.8, OpenSearch versions 1.0 through 1.2, and OpenSearch versions 2.3 through 2.9 for an additional 12 months. Coverage will now continue through November 7, 2027, giving customers additional time to plan and execute their migrations to the latest OpenSearch versions.

From November 7, 2026, the Extended Support surcharge for these versions will effectively double your instance pricing for the extension period. Storage costs are not affected. Elasticsearch 5.6, for which existing Extended Support rates end on November 7, 2028, will continue at the standard Extended Support cost of $0.0065 per Normalized Instance Hour (NIH). During this period, these versions will continue to receive critical security patches and operating system updates.

See the following table for the updated Extended Support end dates.

Software version End of Standard Support Original End of Extended Support date Updated End of Extended Support date
Elasticsearch versions 1.5 and 2.3 November 7, 2025 November 7, 2026 November 7, 2027
Elasticsearch versions 5.1 to 5.5 November 7, 2025 November 7, 2026 November 7, 2027
Elasticsearch version 5.6 November 7, 2025 November 7, 2028 No change
Elasticsearch versions 6.0 to 6.7 November 7, 2025 November 7, 2026 November 7, 2027
Elasticsearch versions 7.1 to 7.8 November 7, 2025 November 7, 2026 November 7, 2027
OpenSearch versions 1.0 to 1.2 November 7, 2025 November 7, 2026 November 7, 2027
OpenSearch versions 2.3 to 2.9 November 7, 2025 November 7, 2026 November 7, 2027

We recommend that you upgrade to the latest available OpenSearch version.

End of Standard Support and Extended Support for additional versions

Today we are announcing end of Standard and Extended Support dates for Elasticsearch versions 6.8, 7.9, and 7.10, OpenSearch version 1.3, and OpenSearch versions 2.11 to 2.19. For future updates on versions in Standard Support and Extended Support, follow supported versions.

For OpenSearch versions running on Amazon OpenSearch Service, we provide at least 12 months of Standard Support after the end-of-support date for the corresponding upstream open source OpenSearch version. Alternatively, we provide 12 months of Standard Support after the release of the next minor version on Amazon OpenSearch Service, whichever is longer. This aligns with the open source OpenSearch maintenance policy.

We categorize these versions into two groups:

  • The last versions of each major version family (ES 6.8, ES 7.10, OS 1.3, OS 2.19) will receive 3 years of Extended Support at the standard Extended Support charge of $0.0065 per NIH.
  • All other minor versions with clear upgrade paths within the same major family (ES 7.9, OS 2.11, OS 2.13, OS 2.15, OS 2.17) will receive 1 year of Extended Support at the same standard rate of $0.0065 per NIH.

After Extended Support ends for a version, domains running that version will not receive bug fixes or security updates. The following table shows the end of Standard Support and Extended Support dates for Elasticsearch and OpenSearch versions.

Elasticsearch versions

Software version End of Standard Support End of Extended Support
Elasticsearch version 6.8 November 7, 2027 November 7, 2030
Elasticsearch version 7.9 November 7, 2027 November 7, 2028
Elasticsearch version 7.10 November 7, 2027 November 7, 2030

OpenSearch versions

Software version End of Standard Support End of Extended Support
OpenSearch version 1.3 November 7, 2027 November 7, 2030
OpenSearch version 2.11 November 7, 2027 November 7, 2028
OpenSearch version 2.13 November 7, 2027 November 7, 2028
OpenSearch version 2.15 November 7, 2027 November 7, 2028
OpenSearch version 2.17 November 7, 2027 November 7, 2028
OpenSearch version 2.19 November 7, 2027 November 7, 2030
OpenSearch version 3.1 and above Not announced Not announced

Upgrading OpenSearch Service domains: We recommend that you upgrade your domains to the latest available OpenSearch version to derive maximum value out of Amazon OpenSearch Service. Minor version upgrades on OpenSearch don’t contain breaking changes. These version upgrades are typically non-disruptive. We recommend moving to the latest minor version. See Upgrading OpenSearch Service domains for detailed instructions. You can also use the Migration Assistant for Amazon OpenSearch Service for upgrading to newer versions.

New domain creation: New domain creation will be blocked after Extended Support ends for each version.

Calculating Extended Support charges

Amazon OpenSearch Service domains running versions under Extended Support will be charged a flat additional fee per NIH. NIH is computed as a factor of the instance size (for example, medium or large), and the number of instance hours.

Depending on which version you are on, the Extended Support charges are as follows:

  • Versions that have been on Extended Support (ES 1.5–7.8 (other than ES 5.6), OS 1.0–1.2, OS 2.3–2.9) from November 7, 2026: Extended Support cost will be equal to your instance price. This will be in addition to the standard instance pricing, effectively doubling the instance cost. Storage costs are not affected. Example (for versions that have been on Extended Support from November 7, 2026): If you are running an m7g.medium.search instance priced at $0.068/hr (on-demand) in US East (N. Virginia) for 24 hours, your standard instance cost is $1.632/day ($0.068×24). The Extended Support surcharge for the extension period will be equal to your instance cost ($1.632/day), doubling your instance pricing to ~$3.264/day. Storage costs remain unchanged.
  • New versions coming under Extended Support (ES 6.8, 7.9, 7.10, OS 1.3, OS 2.11–2.19): $0.0065 per NIH (standard Extended Support rate). See the pricing page for exact pricing by Region. Example (new versions — standard rate): If you are running an m7g.medium.search instance for 24 hours in the US East (N. Virginia) Region, priced at $0.068 per instance hour (on-demand), you will typically pay $1.632 ($0.068×24). If you are running a version that is in Extended Support, you will pay an additional $0.0065 per NIH. This is computed as $0.0065 × 24 (instance hours) × 2 (normalization factor for medium) = $0.312 for Extended Support for 24 hours. The total amount you will pay for 24 hours is $1.944 ($1.632 + $0.312, excluding storage cost).

The following table shows the normalization factor for various instance sizes in OpenSearch Service.

Instance size Normalization Factor
nano 0.25
micro 0.5
small 1
medium 2
large 4
xlarge 8
2xlarge 16
4xlarge 32
8xlarge 64
9xlarge 72
10xlarge 80
12xlarge 96
16xlarge 128
18xlarge 144
24xlarge 192
32xlarge 256

Summary

The latest OpenSearch versions include new features, performance and resiliency improvements, and security enhancements. With today’s announcement, we are:

  • Continuing security and operating system patch coverage for present versions through November 7, 2027, giving customers additional time to complete their upgrades at a new Extended Support rate.
  • Announcing Standard and Extended Support timelines for the next set of versions (ES 6.8, 7.9, 7.10, OS 1.3, 2.11–2.19) with predictable cost visibility.

We recommend that you upgrade to the latest OpenSearch versions to get the most benefit out of OpenSearch Service. For any questions on Standard and Extended Support options, see the FAQs. For further questions, contact AWS Support.


About the authors

Kuldeep Yadav

Kuldeep Yadav

Kuldeep is a Principal Technical Program Manager at AWS. He’s passionate about driving innovation and complex problem solving. He works closely with teams and customers to ensure operational excellence and achieve more with less.

Arvind Mahesh

Arvind Mahesh

Arvind is a Senior Manager-Product at AWS (Amazon OpenSearch Service). With close to two decades of technology experience, he brings deep expertise across Analytics, Search, Cloud, Network Security, and Telecom.

Jon Handler

Jon Handler

Jon is a Senior Principal Solutions Architect at AWS. He works closely with OpenSearch and Amazon OpenSearch Service, guiding a broad range of customers looking to move their search and log analytics workloads to the AWS Cloud.

AWS partners with Anthropic and OpenAI to bring AWS Continuum into developer workflows

Post Syndicated from Chet Kapoor original https://aws.amazon.com/blogs/security/aws-partners-with-anthropic-and-openai-to-bring-aws-continuum-into-developer-workflows/

Customers have access to models that are continuously getting better with each new generation bringing larger context windows, stronger reasoning, and lower token costs. Getting the strongest AI-powered security will come from tools that combine the most relevant models with deep knowledge of a customer’s specific environment.

AWS Continuum for code vulnerabilities (Preview) is built to be that tool to help secure your code at machine speed. Today, we’re announcing a partnership with Anthropic and OpenAI that extends AWS Continuum directly into the developer workflows where code is being written: Anthropic Claude Code, OpenAI Codex, and Kiro. Developers can use these integrations to discover vulnerabilities, contextually prioritize, validate, and remediate, within their existing workflows.

Models are getting smarter

AI models are advancing rapidly. Each generation brings new capabilities, and different models excel at different tasks. The latest frontier models can now identify vulnerabilities and reason through multi-step attack paths that would take a human security team weeks to trace manually.

This is a genuine breakthrough in detection, but it creates a new challenge for your security teams: more findings, more complexity, and the need to determine which ones matter most in your environment and how to address them. The next challenge customers face is building the correct harness and orchestration to turn these models into a single interface that goes from detection through remediation. This is what we set out to do when creating Continuum, which brings together many different models and uses the model that’s most effective for each part of the process.

We also partner with the Frontier Model Forum, an industry consortium developing shared safety standards, evaluation methods, and benchmarking to ensure we can evaluate these models effectively together. We’re also working with model providers on shared security performance benchmarking to make sure we’re using the best model for each task within Continuum and our other AWS security products.

The harness

An AI harness is the orchestration layer that wraps around a model to connect it to tools, guardrails, memory, and workflows, so it delivers outcomes. Think of the model as the engine and the harness as everything around it. You need both to have a high-performance car.

Harnesses are becoming increasingly complex. Teams are stitching together multiple models, agents that call agents, and dynamic workflows, and are dealing with constant change driven by innovations in models, agent frameworks, and tool integrations.

As a result of that complexity, customers are implementing shadow infrastructure to manage integration layers across models and tools. Every time the landscape shifts, security and governance controls potentially break, forcing teams to go back to revisit them and make updates.

These challenges extend beyond the model. They arise in the orchestration required to connect different models and developer environments with tools, context, controls, and workflows across a customer’s environment. At AWS, we see managing that complexity as heavy lifting that AWS should solve. We treat the harness as infrastructure and with the same rigor we apply to identity, discovery, policy enforcement, observability, and compliance of the core infrastructure at AWS.

Enter Continuum

AWS Continuum for code vulnerabilities discovers vulnerabilities, prioritizes them within the context of a customer’s business, validates them in a sandbox, and provides remediation at machine speed. Under the hood, Continuum is an agent-team loop architecture. A sophisticated harness that orchestrates all of it: selecting the right model, connecting to a customer environment, and delivering secure code that’s been validated in context. You never need to think about how the orchestration works, or what changed in the latest release.

Anthropic and OpenAI partnerships

Today we’re announcing partnerships with Anthropic and OpenAI to bring Continuum into the developer workflows where code is being written.

How it works:

Within Claude Code, Codex, and Kiro coding environments, on-demand vulnerability scans identify potential issues and send findings to Continuum. Continuum prioritizes them within the context of the customer’s AWS environment (configurations, AWS Identity and Access Management (IAM) policies, network topology, and exposure surfaces) and validates them in a sandbox. It then returns prioritized, contextual intelligence back to the coding assistant, which adjusts its recommendations accordingly.

This collapses what was traditionally a multi-step, multi-team process (write, scan, triage, prioritize, fix, rescan) into a single outcome: the code suggestion itself. Two modes, one outcome:

  • For existing code: Use Continuum for code vulnerabilities from AWS to discover, prioritize, validate, and remediate across your environment.
  • For greenfield code: Use the Continuum plugin within Codex, Claude Code, or Kiro to get security-validated suggestions in your development environment.

Early design partners are already seeing results.

“AWS Continuum connects source code with enterprise knowledge, allowing teams to accurately pinpoint security vulnerabilities and verify that flagged issues are truly meaningful. This shortens what really matters: timeline to fix serious vulnerabilities.” – Mike Johnson, CISO, Rivian

Next

  • AWS Continuum for code vulnerabilities is available in preview through AWS. Sign up to request access at AWS Continuum.
  • Continuum integrated into Claude Code, Codex, and Kiro workflows are coming soon.

If you have feedback about this post, submit comments in the Comments section below.


Chet Kapoor

Chet Kapoor

Chet is Vice President of Search, Security, and Observability at Amazon Web Services. With more than two decades in enterprise technology, he has led companies through some of the industry’s most consequential platform shifts — from APIs and open source to cloud and AI — building and scaling businesses through periods of rapid growth, transformation, acquisition, and IPO. He brings a builder’s mindset, deep operational experience, and a strong customer orientation to helping organizations adopt emerging technologies securely and at scale.

From 2 weeks to 2 minutes: Amazon Cognito launches Provisioned limits for self-service rate limit management

Post Syndicated from Kiran Dongara original https://aws.amazon.com/blogs/security/from-2-weeks-to-2-minutes-amazon-cognito-launches-provisioned-limits-for-self-service-rate-limit-management/

Imagine preparing for your biggest sales event of the year, and you want to ensure your customer identity management service can handle the elevated traffic for carrying out application activities. For security teams, business leaders, and technologists managing identity infrastructure at scale, this scenario has been all too familiar. Whether you’re a CISO evaluating security controls, a CFO managing cloud costs, traditional support ticket processes for adjusting Amazon Cognito rate limits meant waiting 10–14 days for capacity increases, requiring teams to plan weeks in advance or rush to escalate.

Today, we’re announcing provisioned limits for Amazon Cognito, a capability that transforms how you manage authentication rate limits. This introduces a feature in the AWS Management Console for Amazon Cognito for on-demand capacity adjustments, working alongside the existing account-level maximum limits in AWS Service Quotas. Together, they give you self-service control over your authentication infrastructure so you can scale up for Black Friday (or similar sales events), scale down after tax season, and optimize costs with unprecedented precision. What once took up to 2 weeks now happens in minutes.

In this post, you’ll learn how provisioned limits work, the relationship between account-level maximums and provisioned capacity, the cost implications and optimization strategies, and step-by-step implementation guidance. This capability fundamentally changes how you approach authentication capacity planning.

Manual processes that can’t keep pace

Identity management services open the front door to your application. When users can’t sign in, everything else stops. Amazon Cognito offers extremely flexible limit management: customers can request adjustments as granular as 1 request per second (RPS) for as short as 1 day. As customer demand for faster, self-service adjustments grew, we identified opportunities to address the following challenges:

  • Support tickets required for each rate limit change
  • 10–14 day approval timelines for standard review and processing
  • Advance planning needed weeks ahead of anticipated traffic spikes

For businesses with seasonal traffic, like tax preparation services that see 90% of annual authentication volume in March and April, or ecommerce platforms preparing for Black Friday, these factors meant teams had to plan capacity decisions well in advance with limited ability to adjust in the moment.

Provisioned limits and account-level max limits

Starting July 6, 2026, Amazon Cognito introduced provisioned limits in the Amazon Cognito console. At the account level (per AWS Region, per account), you’ll find a Provisioned limits tab next to the User Pools tab. This gives you direct control over your authentication rate limits through two complementary mechanisms:

  • Provisioned limits (Amazon Cognito console) – Adjust your provisioned capacity up or down on-demand. Changes take effect immediately. You’re billed for the capacity you provision above the default limit, regardless of how much you use.
  • Account-level max limit (Service Quotas console) – Set your account’s ceiling, the maximum RPS your account is allowed to provision. Raising this ceiling doesn’t incur additional charges. Approximately 90% of requests are automatically approved within minutes. For larger limit increases (depending on the API category and Region), manual approval through AWS Support might still be required.

The following experience shows the end-to-end workflow of adjusting your provisioned limits and requesting a higher account-level max.

Figure 1: Provisioned limit experience workflow

Figure 1: Provisioned limit experience workflow

How they work together

Let’s use the UserCreation API as an example. The default limit is 50 RPS, and initially the provisioned limit is also 50 RPS—meaning billed capacity is 0 (no additional charge). The applied account-level max limit is also 50 RPS. So you have three values: default (50), provisioned limit (50), and account-level max (50).

  1. Start by going to the Amazon Cognito console and choosing User pools from the navigation pane.

    Figure 2: UserCreation with default values

    Figure 2: UserCreation with default values

  2. Choose Edit provisioned limit, to go to the Edit provisioned limit page with an input field for New provisioned limit. However, because the account-level max limit is 50 RPS, you can’t set the provisioned limit above 50. For example, if you want to provision 55 RPS, the console won’t allow it because 55 exceeds the current account max of 50.

    Figure 3: Editing the provisioned limit constraint constraint to more than the account-level max

    Figure 3: Editing the provisioned limit constraint constraint to more than the account-level max

  3. To set a higher limit, choose Request an increase. This takes you to the Service Quotas console, where you can choose Request increase at account level to request a higher account-level max, for example, 55 RPS. Most requests are automatically approved within minutes. At any time, you can check the status of the request using the Request history tab.

    Figure 4: Service Quotas page where the account-level max increase is requested and auto-approved

    Figure 4: Service Quotas page where the account-level max increase is requested and auto-approved

  4. After receiving approval, return to the Amazon Cognito console to edit your provisioned limit up to 55 RPS. Your billed capacity becomes 5 RPS (55 minus the 50 default).

    Figure 5: Provisioned after increasing the provisioned limit to 55 RPS, with billed capacity of 5 RPS.

    Figure 5: Provisioned after increasing the provisioned limit to 55 RPS, with billed capacity of 5 RPS.

This two-part model gives you precise control over both cost and capacity. Raising the account-level max in Service Quotas doesn’t incur additional charges—it only sets your ceiling. You are billed for what you provision in the Amazon Cognito console above the default, so you benefit from right-sizing your provisioned capacity to match expected demand. Raise your account max ahead of time to prepare for future scaling needs without incurring any cost. When the time comes, increase your provisioned limit to what you need, and scale back down after the event. You stop being charged for the extra capacity as soon as you reduce the provisioned limit. This applies equally to seasonal spikes, planned load tests, or unexpected viral growth—all self-service, all within minutes.

How the provisioned limits experience works

The provisioned limits experience introduces three key concepts that work together:

  • Default limit – The baseline rate included at no additional cost (for example, 50 RPS for UserCreation).
  • Provisioned limit – The capacity you actively request and reserve in the Amazon Cognito console. Because this capacity is reserved specifically for your account, it’s the chargeable dimension. You’re billed for any provisioned capacity above the default, regardless of how much you consume. For example, if the default is 50 RPS and you provision 80 RPS, you’re billed for 30 RPS even if your actual usage is only 60 RPS. If your provisioned capacity is 50 RPS (the default), your billed capacity is 0.
  • Applied account-level max limit – The ceiling managed through Service Quotas. This determines how high you can set your provisioned limit. Raising this ceiling doesn’t incur charges, it only unlocks the ability to provision higher capacity. Importantly, the Provisioned limits page displays each API category with its adjustability status. For example, UserCreation is marked Adjustable (shown earlier in Figure 5) and can be modified. However, UserList is marked Not adjustable, meaning the account-level max limit can’t be adjusted for that category. You can still see its default and provisioned limit on the page, but you can’t modify them. For adjustable categories, you will see the default limit, current provisioned limit, and billed capacity at a glance.
Figure 6: Provisioned limits overview with non-adjustable API categories.

Figure 6: Provisioned limits overview with non-adjustable API categories.

Multi-tenant SaaS considerations

For software as a service (SaaS) providers managing multiple tenants with varying throughput requirements, the UpdateProvisionedLimit API enables programmatic management of provisioned capacity. Teams using dedicated user pools per tenant, for example, can integrate this into their infrastructure-as-code pipelines to adjust provisioned limits per tenant tier. With provisioned limits, SaaS vendors can tier their capacity management per tenant, for example, provisioning higher capacity for enterprise-tier tenants and lower capacity for free-tier tenants, and adjust each tenant’s provisioned capacity independently through the API based on their service tier and demand patterns.

Conclusion

With provisioned limits, whether you’re preparing for peak shopping season, tax filing deadlines, or any other scaling event, you can now adjust provisioned limits to respond to your organization’s needs on demand. The separation between the account-level max (in Service Quotas) and the provisioned limit (in the Amazon Cognito console) gives you full control to plan ahead, respond to demand changes in minutes, and optimize costs on your own terms.

Get started

The provisioned limits experience for Amazon Cognito user pools launched on July 6, 2026, and is available across all AWS Regions where Amazon Cognito is supported. To get started:

  1. Review your current authentication traffic patterns using Amazon CloudWatch metrics to understand your baseline
  2. Set up CloudWatch alarms at 70% and 85% of your current rate limits
  3. Ensure your team has appropriate AWS Identity and Access Management ( IAM) permissions for both Service Quotas and the Provisioned limits tab in the Amazon Cognito console
  4. Raise your account-level max in Service Quotas based on your demand expectations
  5. Use the Amazon Cognito console Provisioned limits tab to adjust capacity up or down as needed

Resources:

Need help? Contact your AWS account team or visit AWS Support for assistance with planning your rate limit strategy.

If you have feedback about this post, submit comments in the Comments section below.


Kiran Dongara

Kiran is an Enterprise Solutions Architect at AWS, primarily supporting Retail, Restaurant, and CPG customers. His primary focus is application identity within the IAM domain. His expertise includes deep technical understanding across technical and industry domains, which he integrates to design scalable and efficient architectures using best practices. When not working, Kiran prioritizes family time, nature walks, and cycling.

Howie Li

Howie Li

Howie Li is a Product Manager at Amazon Web Services, where he strives to make authentication straightforward by default. Outside of work, Howie enjoys exploring cultures and food through travels and making new ice cream flavors inspired by them.

Amazon DynamoDB now supports real-time vector search at any scale

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/amazon-dynamodb-now-supports-real-time-vector-search-at-any-scale/

Today, we’re announcing the general availability of vector search in Amazon DynamoDB. You can now store vector embeddings alongside your operational data in DynamoDB and run similarity searches directly against that data, without replicating it to a separate vector store.

DynamoDB supports native vector search with single-digit millisecond latency at 99%+ recall, and is designed for any scale, even trillions of vectors. There are no servers to provision, patch, or manage, and no software to install, maintain, or operate. The service has no versions, no maintenance windows, and zero downtime maintenance.

Vector indexes have no storage limits and scale horizontally as your data grows. You can now build applications that require semantic retrieval on agentic memory, retrieval augmented generation, recommendation engines, personalized experiences, anomaly detection, and more using DynamoDB and its native vector search.

If your application already uses DynamoDB, adding vector search previously required copying data into a dedicated vector database while maintaining a synchronization pipeline between the two services. This added operational overhead, data movement costs, licensing costs, and the challenge of maintaining predictable low latency at scale. With vector search built into DynamoDB, your vectors and operational data share the same serverless infrastructure and the same pay-per-request pricing model.

Vector search in DynamoDB introduces a new index type that you create on an attribute storing vector embeddings. You generate embeddings using a model of your choice, such as Amazon Bedrock Titan Text Embeddings, Cohere Embed, or OpenAI text embedding models, and store them as a list of floats in your table using a standard PutItem call. You then create a vector index on that attribute and specify the number of dimensions, the distance function, and any non-vector attributes you want to use as filters to narrow search results at query time. The SearchVectors API accepts a query vector, the number of results to return (up to 100), and optional filter conditions. It returns results ranked by similarity.

Use vector search in DynamoDB when your operational data already lives in DynamoDB and you want to add similarity search without provisioning a separate database or managing a synchronization pipeline. DynamoDB is fully serverless, so vector search scales automatically with no infrastructure to manage. It supports up to 4096 dimensions, Euclidean, Cosine, and Dot product distance functions, and inline filtering.

Getting started with vector search in DynamoDB
This walkthrough shows how to add vector search to an existing DynamoDB table using the DynamoDB console. The scenario contains an online sporting goods store with a product catalog table. Each item has standard operational attributes such as productId, category, description, marketplace, name, and price. The goal is to add semantic search so shoppers can find products using natural language queries rather than exact keyword matches.

1. Prepare DynamoDB table
To enable semantic search, I first generate vector embeddings for the product descriptions already in my table. Embeddings are numerical representations of text generated by a machine learning model that capture the meaning of the content. Two items with similar descriptions will have embeddings that are close to each other in vector space, which is what makes similarity search possible.

I can generate embeddings using Amazon Bedrock Titan Text Embeddings or another embedding model, then add them to my table using the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS SDKs, AWS CloudFormation, or other infrastructure-as-code (IaC) tools.

For an existing table like ProductCatalog, I add the embeddings to each item as a new attribute named descriptionEmbedding using an UpdateItem call. DynamoDB stores vector embeddings using its existing List data type. Each element in the list is a Number that represents a single float value of the embedding vector. This means I do not need a new data type or schema change to start storing vectors alongside my existing operational attributes.

2. Create vector index
In the DynamoDB console, open the ProductCatalog table and choose the Indexes tab. I choose Create vector index. On the Create vector index page, I fill in the index details as follows. I enter ProductDescriptionIndex as the Index name and descriptionEmbedding as the Vector attribute.

I enter the number of Dimensions that matches my embedding model’s output and select Cosine as the Distance function. Cosine measures the angle between vectors rather than their magnitude, which makes it effective for comparing semantic similarity of text embeddings. Vector search in DynamoDB also supports Euclidean and Dot product distance functions.

  • Euclidean: Use when the magnitude of the vectors is meaningful, such as clustering items by a numeric value like purchase count.
  • Dot product: Use when both direction and magnitude matter, such as in recommendation systems that weight interest alignment and frequency together. As a general rule, match the distance function to the one used to train your embedding model for the best accuracy.

I enter marketplace as the Partition key. The vector index partition key controls how DynamoDB distributes vectors across partitions, allowing the index to scale out while maintaining predictable latencies. Each search is scoped to a single partition key value, so a product catalog serving multiple marketplaces can search within one marketplace’s inventory without scanning the entire index. The partition key is optional, but recommended for large datasets with high query throughput.

I expand Inline filter attributes and add category as a filter attribute. This helps me narrow search results to a specific product category at query time. Filter conditions support exact-match values only; range conditions such as BETWEEN or BEGINS_WITH are not supported. I leave Attribute projections set to All so that all table attributes are returned with my search results. Choose Create vector index and wait for the index status to change to Active.

3. Run vector search
I generate a query vector from a natural language search term such as “lightweight running shoes for summer” using the same embedding model I used for the product descriptions. In the DynamoDB console, I choose Explore items in the left navigation pane and select the ProductCatalog table.

Choose Search to switch to vector search mode. I select ProductDescriptionIndex from the Select a vector index dropdown, paste the query vector into the Search vector field, and set Number of results (Top K) to 5. I enter US as the Partition key value to scope the search to the US marketplace. I expand Inline filter attributes and set category equal to footwear to narrow the search to footwear products only. Now, choose Run.

DynamoDB returns the five most semantically similar products in the footwear category, ranked by similarity score, alongside the standard operational attributes such as name and price in the same response. The similarity score’s meaning depends on the distance function selected for the index. For Cosine and Euclidean distance functions, lower similarity score values indicate higher similarity, with a score of 0 indicating identical vectors. For the dot product distance function, higher similarity score values indicate higher similarity.

To interact with vector search programmatically, including calling APIs and searching documentation, try the AWS MCP Server and plugins with your preferred AI coding tool. To learn more, visit the Amazon DynamoDB Developer Guide.

Get started today
Vector search in Amazon DynamoDB is generally available in all commercial AWS Regions, including the AWS GovCloud (US) Regions. For Regional availability and a future roadmap, visit the AWS Capabilities by Region. For pricing details, visit the Amazon DynamoDB pricing page.

Start exploring vector search in DynamoDB today and send feedback to AWS re:Post for Amazon DynamoDB or through your usual AWS Support contacts.

— Esra

Spring 2026 PCI DSS and PCI 3DS compliance packages for AWS now available

Post Syndicated from Will Black original https://aws.amazon.com/blogs/security/spring-2026-pci-dss-and-pci-3ds-compliance-packages-for-aws-now-available/

Amazon Web Services (AWS) is pleased to announce the successful completion of our Payment Card Industry (PCI) Data Security Standard (DSS) and Three Domain Secure (3DS) certifications. As part of this renewal, we have expanded the scope to include three additional AWS services and one additional AWS Region:

Newly added AWS services:

Newly added AWS Region:

  • Asia Pacific – New Zealand

This certification means that customers can use these services while maintaining PCI DSS and PCI 3DS compliance, enabling innovation without compromising security. The full list of services can be found on the AWS Services in Scope by Compliance Program page.

The PCI DSS and PCI 3DS compliance packages include two key components for each certification:

  • Attestation of Compliance (AOC) – demonstrates that AWS was successfully validated against the PCI DSS and PCI 3DS standards.
  • AWS Responsibility Summary – provides guidance to help AWS customers understand their responsibility in developing and operating a highly secure environment on AWS for handling payment card data.

AWS was evaluated by Coalfire, a third-party Qualified Security Assessor (QSA).

This refreshed certification offers customers greater flexibility in deploying regulated workloads while reducing compliance overhead. Customers can access the PCI DSS and PCI 3DS report packages through AWS Artifact. This self-service portal provides on-demand access to AWS compliance reports, streamlining audit processes.

To learn more about our PCI programs and other compliance and security programs, see the AWS Compliance Programs page.

As always, we value your feedback and questions; reach out to the AWS Compliance team through the Compliance Support page.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.


Will Black

Will Black

Will is a Compliance Program Manager at AWS where he leads multiple security and compliance initiatives. Will has 10 years of experience in compliance and security assurance and holds a degree in Management Information Systems from Temple University. Additionally, he is a PCI Internal Security Assessor (ISA) for AWS and holds the CCSK and ISO 27001 Lead Implementer certifications.

Introducing Apache Spark troubleshooting agent for Amazon EMR on EKS

Post Syndicated from Vara Bonthu original https://aws.amazon.com/blogs/big-data/introducing-apache-spark-troubleshooting-agent-for-amazon-emr-on-eks/

Debugging a failed Apache Spark application on Amazon EMR on EKS often means correlating signals from several places at once. These signals include Spark driver and executor pod logs, Spark event logs, and container termination signals that surface as pod exit codes rather than clear Spark errors. For example, a single out-of-memory failure can appear as a Kubernetes exit code 137 with no obvious link back to the line of code or configuration that caused it. This cross-system investigation can extend a single incident’s mean-time-to-resolution (MTTR) to days and requires deep Spark and Kubernetes expertise.

We recently announced Amazon EMR on EKS now supports Apache Spark troubleshooting agent extending the Apache Spark troubleshooting agent to support Amazon EMR on EKS. The agent already helps data engineers diagnose Spark failures on Amazon EMR on EC2, Amazon EMR Serverless, and AWS Glue using natural language prompts. With this launch, you can now point the same workflow at a failed Amazon EMR on EKS job run. From a single natural language prompt, the agent automatically retrieves your Spark logs from Amazon Simple Storage Service (Amazon S3) or Amazon CloudWatch (depending on your job’s logging configuration) along with Spark History Server Event log data, identifies the root cause, and recommends a fix when the failure is code-related. This can help reduce incident MTTR from days to minutes. Amazon EMR on EKS customers can use the agent at no additional cost. You only pay for your existing Amazon EMR on EKS resources.

In this post, we show you how to set up the agent for Amazon EMR on EKS and walk through troubleshooting a failed job run. We demonstrate the workflow from both the Amazon EMR console and an AI assistant that supports the Model Context Protocol (MCP), an open standard for connecting AI assistants to external tools and data.

How the troubleshooting agent works on Amazon EMR on EKS

The troubleshooting agent exposes a single interface to diagnose failed Spark applications across Amazon EMR on EKS, Amazon EMR on EC2, Amazon EMR Serverless, AWS Glue, and Amazon SageMaker notebooks. Instead of navigating different consoles, APIs, and log locations for each service, you describe your failed job in natural language, and the agent handles the rest. You can reach the agent from the Amazon EMR console or from MCP-compatible AI assistants, such as Kiro CLI, Kiro IDE, or Claude Code. We walk through both later in this post.

The troubleshooting agent runs as a fully managed MCP server, so you do not need to deploy or maintain a local MCP server. It uses a single-tenant design to keep your application data and code isolated. Operations are read-only and governed by AWS Identity and Access Management (IAM) permissions. The agent can only access the resources and actions your IAM role grants. Tool calls are automatically logged to AWS CloudTrail for complete auditability.

Architecture of the Spark troubleshooting agent running as a managed MCP server with read-only IAM access and CloudTrail logging

What’s specific to Amazon EMR on EKS is how the agent gathers its inputs. On Amazon EMR on EKS, your Spark driver and executor logs can be delivered to Amazon S3, Amazon CloudWatch Logs, or both, depending on your job’s monitoring configuration. The agent handles both sources automatically:

  • Driver and executor pod logs in Amazon S3 – When your job is configured with S3 monitoring, the agent reads the Spark event logs and the per-container stderr/stdout logs from your S3 log location, including discovering executor pod logs.
  • Driver and executor container logs in Amazon CloudWatch – When your job is configured with CloudWatch monitoring, the agent reads the driver and executor container log streams directly from your CloudWatch log group.
  • Spark History Server (SHS) data through the Amazon EMR Persistent UI – For the richer SHS signals (query plans, executor timelines, stage metrics, and configurations), the agent connects to the Amazon EMR Persistent UI for your job run, the same mechanism used for Amazon EMR on EC2.

Drawing on years of AWS experience running millions of Spark applications at scale, the agent extracts the relevant features and signals from these sources, work that would otherwise require manual correlation across Amazon S3, Amazon CloudWatch, and the Spark UI. It then uses a large language model on Amazon Bedrock, grounded in a managed knowledge base of Spark and AWS troubleshooting expertise through Retrieval Augmented Generation (RAG), to produce a root cause analysis and, when the failure is code-related, a code recommendation.

The large language model (LLM), the knowledge base, and the retrieval that connects them are fully managed as part of the agent. There’s nothing for you to provision, host, or tune. This managed inference is provided at no additional cost for Amazon EMR on EKS. You pay only for the AWS resources you already use to run your Spark applications and to validate recommended changes.

The agent extracting signals from Amazon S3 and Amazon CloudWatch and using an Amazon Bedrock model with a knowledge base to produce a root cause analysis

Getting started

You can use the agent from either the Amazon EMR console or an MCP client. Both rely on setting up a single IAM role. The following sections walk through creating that role and then troubleshooting a failed job run with each method.

Set up IAM permissions

The IAM role grants the agent read access to the diagnostic sources it analyzes, such as your Amazon EMR on EKS job runs, the Amazon EMR Persistent UI, and your Spark logs in Amazon S3 and Amazon CloudWatch. Creating this role is the only setup required for the console experience. The MCP client path has a few additional prerequisites, covered later in the section on troubleshooting from an MCP client.

To run the commands in this section, you need the AWS Command Line Interface (AWS CLI) (version 2.30.0 or later) installed and configured with your AWS credentials. For instructions, see Setting up the AWS CLI.

Step 1: Create the IAM role

The agent uses your IAM role to authorize operations at the AWS service level. It can only access what your role allows. Create a role your account can assume, then attach a policy granting the permissions the agent needs for Amazon EMR on EKS.

First, set some variables for the commands that follow. ACCOUNT_ID is derived from your configured credentials. Set REGION to the AWS Region where you run your Amazon EMR on EKS workloads:

ACCOUNT_ID=$(aws sts get-caller-identity --query Account --output text)
REGION=us-east-2   # replace with your Region

Create a trust policy that allows your account to assume the role, and create the role:

cat > mcp-trust-policy.json << EOF
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowAccountToAssumeRole",
      "Effect": "Allow",
      "Principal": { "AWS": "arn:aws:iam::${ACCOUNT_ID}:root" },
      "Action": "sts:AssumeRole"
    }
  ]
}
EOF

aws iam create-role \
  --role-name SparkTroubleshootingMCPRole \
  --assume-role-policy-document file://mcp-trust-policy.json

Step 2: Attach Amazon EMR on EKS permissions

Create and attach a policy granting the agent read access to your Amazon EMR on EKS job runs, the Amazon EMR Persistent UI, and your S3 and CloudWatch logs. Replace amzn-s3-demo-logging-bucket with the name of your logging bucket and replace my_log_group_name and my_log_stream_prefix with your CloudWatch log group name and log stream prefix, respectively.

cat > emr-eks-policy.json << EOF
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "EMREKSReadAccess",
      "Effect": "Allow",
      "Action": [
        "emr-containers:DescribeJobRun",
        "emr-containers:DescribeVirtualCluster",
        "emr-containers:ListJobRuns",
        "emr-containers:ListVirtualClusters"
      ],
      "Resource": ["*"]
    },
    {
      "Sid": "EMREKSPersistentApp",
      "Effect": "Allow",
      "Action": [
        "elasticmapreduce:CreatePersistentAppUI",
        "elasticmapreduce:DescribePersistentAppUI",
        "elasticmapreduce:GetPersistentAppUIPresignedURL"
      ],
      "Resource": ["*"]
    },
    {
      "Sid": "EMREKSS3LogAccess",
      "Effect": "Allow",
      "Action": ["s3:GetObject", "s3:ListBucket"],
      "Resource":[
        "arn:aws:s3:::amzn-s3-demo-logging-bucket",
        "arn:aws:s3:::amzn-s3-demo-logging-bucket/*"
      ]
    },
    {
      "Sid": "EMREKSCloudWatchLogAccess",
      "Effect": "Allow",
      "Action": [
        "logs:GetLogEvents",
        "logs:DescribeLogGroups",
        "logs:DescribeLogStreams"
      ],
      "Resource": [
        "arn:aws:logs:*:*:log-group:my_log_group_name:log-stream:my_log_stream_prefix/*"
      ]
    }
  ]
}
EOF

aws iam put-role-policy \
  --role-name SparkTroubleshootingMCPRole \
  --policy-name EMREKSTroubleshootingAccess \
  --policy-document file://emr-eks-policy.json

Note: If you prefer an automated setup, an AWS CloudFormation template that creates this role with the required permissions is available in the setup documentation. The previous CLI steps give you the same result with finer control over each permission.

Troubleshooting a failed Amazon EMR on EKS job run

You can reach the troubleshooting agent two ways: directly from the Amazon EMR console, or from an MCP-compatible AI assistant such as Claude Code. We walk through both, using two different failures to show the range of what the agent diagnoses.

Option 1: Troubleshoot from the Amazon EMR console

The console offers the fastest path. Once you’ve created the IAM role in the Set up IAM permissions section, no additional setup is required. Here we troubleshoot a job that failed with a driver out-of-memory error. The application generates a large dataset and calls collect() to pull it back to the driver, exceeding the configured spark.driver.maxResultSize of 512 MiB.

  1. Open the Amazon EMR console, choose Virtual clusters (under Amazon EMR on EKS), and select the virtual cluster that ran your job.
  2. In the Jobs list, find your failed job run and choose its Failed status. This opens a popover with a Troubleshoot with AI button.

The failed job run popover in the Amazon EMR console with the Troubleshoot with AI button

  1. Choose Troubleshoot with AI. The agent analyzes the job and returns its findings directly on the console, namely the analysis insights, a root cause, and a recommendation. For this job, it identifies that the collect() operation on line 24 attempts to materialize the full result set on the driver, exceeding the spark.driver.maxResultSize safety limit. This fails the job before an actual driver out-of-memory crash. Because the failure stems from the application code, the agent also returns a code recommendation: a before-and-after diff that replaces the collect() call with a distributed write to the destination path. Executors then persist their partitions in parallel instead of funneling the data through the driver.

Agent results in the console showing the root cause and a before-and-after code recommendation for the collect() failure

Option 2: Troubleshoot from an MCP client (Claude Code)

You can also use the agent from MCP-compatible AI assistants. This option requires a one-time setup to connect the assistant to the agent’s MCP servers, and it unlocks a conversational workflow where the agent chains from analysis into a concrete code fix. In this walkthrough, we use Claude Code.

Prerequisites

In addition to the IAM role from the Set up IAM permissions section, the MCP client path requires:

  • Python 3.10 or higher.
  • The uv package manager. For instructions, see Installing uv.
  • Claude Code installed. For instructions, see Install Claude Code. You can also use another MCP-compatible AI assistant such as Kiro CLI or Kiro IDE.

Configure an AWS CLI profile

Configure a profile that assumes the IAM role you created, so the MCP servers call AWS with the agent’s permissions:

export IAM_ROLE=arn:aws:iam::${ACCOUNT_ID}:role/SparkTroubleshootingMCPRole
export SMUS_MCP_REGION=${REGION}

aws configure set profile.smus-mcp-profile.role_arn ${IAM_ROLE}
aws configure set profile.smus-mcp-profile.source_profile default
aws configure set profile.smus-mcp-profile.region ${SMUS_MCP_REGION}

Add the MCP servers

The troubleshooting agent provides two tools through two MCP servers: analyze_spark_workload (workload analysis and root cause) and spark_code_recommendation (code fixes). Add both to your assistant.

For Claude Code:

claude mcp add sagemaker-unified-studio-mcp-troubleshooting \
    -- uvx mcp-proxy-for-aws@latest \
    https://sagemaker-unified-studio-mcp.${SMUS_MCP_REGION}.api.aws/spark-troubleshooting/mcp \
    --service sagemaker-unified-studio-mcp --profile smus-mcp-profile \
    --region ${SMUS_MCP_REGION} --read-timeout 180

claude mcp add sagemaker-unified-studio-mcp-code-rec \
    -- uvx mcp-proxy-for-aws@latest \
    https://sagemaker-unified-studio-mcp.${SMUS_MCP_REGION}.api.aws/spark-code-recommendation/mcp \
    --service sagemaker-unified-studio-mcp --profile smus-mcp-profile \
    --region ${SMUS_MCP_REGION} --read-timeout 180

Verify your setup by running the /mcp command in Claude Code to confirm the sagemaker-unified-studio-mcp-troubleshooting and sagemaker-unified-studio-mcp-code-rec servers are connected and their tools are available.

For Kiro CLI:

# Add the Spark Troubleshooting MCP server
kiro-cli-chat mcp add \
    --name "sagemaker-unified-studio-mcp-troubleshooting" \
    --command "uvx" \
    --args "[\"mcp-proxy-for-aws@latest\",\"https://sagemaker-unified-studio-mcp.${SMUS_MCP_REGION}.api.aws/spark-troubleshooting/mcp\", \"--service\", \"sagemaker-unified-studio-mcp\", \"--profile\", \"smus-mcp-profile\", \"--region\", \"${SMUS_MCP_REGION}\", \"--read-timeout\", \"180\"]" \
    --timeout 180000 \
    --scope global

# Add the Spark Code Recommendation MCP server
kiro-cli-chat mcp add \
    --name "sagemaker-unified-studio-mcp-code-rec" \
    --command "uvx" \
    --args "[\"mcp-proxy-for-aws@latest\",\"https://sagemaker-unified-studio-mcp.${SMUS_MCP_REGION}.api.aws/spark-code-recommendation/mcp\", \"--service\", \"sagemaker-unified-studio-mcp\", \"--profile\", \"smus-mcp-profile\", \"--region\", \"${SMUS_MCP_REGION}\", \"--read-timeout\", \"180\"]" \
    --timeout 180000 \
    --scope global

Verify with the /tools command in Kiro CLI to confirm the analyze_spark_workload and spark_code_recommendation tools are available.

Run the agent

For this walkthrough, we troubleshoot a different failure to show how the agent chains from analysis into a concrete code fix. The job is a small PySpark application that reads a CSV file into a DataFrame and registers it as a temporary view named people. It runs a Spark SQL query to uppercase the Name column before displaying the results. The job run failed because the query calls UPPERX, a function that doesn’t exist in Spark SQL (it’s a typo for the built-in UPPER).

From the Claude Code terminal (or MCP-compatible assistants), describe your failed job run in natural language, providing the virtual cluster ID and job run ID:

Debug my EMR on EKS job with job run id <jr-id> and virtual cluster id <vc-id> in <region>

The agent invokes the analyze_spark_workload tool, which automatically:

  1. Calls the Amazon EMR on EKS API to retrieve your job run’s configuration and determine where its logs are stored.
  2. Retrieves your Spark logs from Amazon S3 or Amazon CloudWatch, depending on your job’s logging configuration.
  3. Connects to the Amazon EMR Persistent UI to extract Spark UI features such as the execution plan, stage metrics, and executor timelines.
  4. Analyzes the correlated signals and returns a root cause explanation.

For this job, the agent returns:

Root cause: SQL function error. Your Spark SQL query references a function UPPERX that doesn’t exist in an available function catalog (system.builtin, system.session, or spark_catalog.default). Category: SQL_ERROR. The job failed because the function name can’t be resolved. UPPERX is almost certainly a typo for the built-in UPPER function.

Because the failure is code-related, the agent then chains into the spark_code_recommendation tool, which produces a concrete before-and-after fix:

  df.createOrReplaceTempView("people")

- result = spark.sql("SELECT UPPERX(Name) FROM people")
+ result = spark.sql("SELECT UPPER(Name) FROM people")
  result.show()

  spark.stop()

The two tools work together. analyze_spark_workload identifies the root cause, and when the failure stems from the application code, spark_code_recommendation returns the exact edit to make. You review the recommendation and apply it with full control over the change. The agent only provides the analysis and recommendations.

Supported failure categories

The troubleshooting agent diagnoses a wide range of Apache Spark failures on Amazon EMR on EKS, including:

  • Out-of-memory and resource exhaustion – Driver and executor out-of-memory errors, including driver-side failures from operations like collect() and executor terminations that surface as Kubernetes pod exit codes (such as exit code 137).
  • Data skew and shuffle issues – Uneven partitioning and shuffle failures that concentrate work on a few executors.
  • Configuration errors – Misconfigured Spark settings that lead to failures or inefficiency.
  • Code-level issues – Problems such as incorrect API usage, unbounded collect() calls, and user-defined function (UDF) errors, for which the agent can recommend code fixes.

Code recommendations are supported for PySpark workloads on Amazon EMR on EKS, Amazon EMR on EC2, Amazon EMR Serverless, and AWS Glue.

Conclusion

With support for Amazon EMR on EKS, the Apache Spark troubleshooting agent gives platform and data engineering teams a shared workflow for investigating failed Spark applications. By bringing together Spark and Kubernetes diagnostic signals, the agent can reduce manual investigation and repeated handoffs between teams, helping engineers identify likely causes and corrective actions faster.

There’s no additional charge for using the troubleshooting agent, including the large language model used through Amazon Bedrock. You pay only for the AWS resources used to run your Spark applications and validate recommended changes.

To get started:


About the authors

Vara Bonthu

Vara Bonthu

Vara is a Principal Open Source Specialist SA leading Data on EKS at AWS, driving open source initiatives and helping AWS customers to diverse organizations. He specializes in open source technologies, data analytics, AI/ML, and Kubernetes, with extensive experience in development, DevOps, and architecture.

Maheedhar Reddy Chappidi

Maheedhar Reddy Chappidi

Maheedhar is a Senior Software Development Engineer at AWS Analytics. He is passionate about building fault-tolerant, reliable distributed systems at scale and generative AI applications for data integration. Outside of work, Maheedhar enjoys listening to podcasts and playing with his two-year-old child.

Layth Yassin

Layth Yassin

Layth is a Software Development Engineer at AWS Analytics. He’s passionate about building distributed systems and generative AI solutions for data integration problems. Outside of work, he enjoys playing/watching basketball, and spending time with friends and family.

Andrew Kim

Andrew Kim

Andrew is a Software Development Engineer at AWS Analytics, with a deep passion for distributed systems architecture and AI-driven solutions, specializing in intelligent data integration workflows and cutting-edge feature development on Apache Spark. Andrew focuses on re-inventing and simplifying solutions to complex technical problems, and he enjoys creating side projects and producing music in his free time.

Kartik Panjabi

Kartik Panjabi

Kartik is a Software Development Manager at AWS Analytics. His team builds generative AI features for the Data Integration and distributed system for data integration.

Weijing Cai

Weijing Cai

Weijing is a Software Development Engineer at AWS Analytics. She is passionate about distributed systems and generative AI, and their intersection in building intelligent, scalable solutions for data integration.

Jeremy Samuel

Jeremy Samuel

Jeremy is a Software Development Engineer at AWS Analytics. He has a strong interest in creating distributed systems and generative AI. In his spare time, he enjoys playing video games and listening to music.

Shawn Huang

Shawn Huang

Shawn is a Software Engineer working on the Amazon EMR on EKS service, where he develops scalable and reliable solutions for running big data workloads on Kubernetes.

Siddharth Kumar

Siddharth Kumar

Siddharth is a Software Development Engineer for Amazon EMR at Amazon Web Services, where he works across the Amazon EMR on EKS service. He helps build and operate the systems that let customers run Spark workloads on Amazon Elastic Kubernetes Service (Amazon EKS) at scale, with a focus on making them easier to run, monitor, and scale. Outside of work, Siddharth enjoys watching anime, swimming, and hiking.

HIPAA Security Rule on AWS – Technical Safeguards Implementation and Readiness Guidance

Post Syndicated from Abdul Javid original https://aws.amazon.com/blogs/security/hipaa-security-rule-on-aws-technical-safeguards-implementation-and-readiness-guidance/

Today, we’re releasing the HIPAA Security Rule on AWS: Technical Safeguards Implementation and Readiness Guidance. This helps covered entities and business associates configure, implement, and evidence compliance with the HIPAA Security Rule Technical Safeguard requirements (45 CFR §164.312) when building healthcare workloads on AWS.

The HIPAA Security Rule’s Technical Safeguards (§164.312) define five standards and nine implementation specifications covering access control, audit controls, integrity, authentication, and transmission security.

The guidance also covers the 2025 NPRM proposed changes, including encryption at rest and in transit becoming required, multi-factor authentication (MFA) becoming mandatory for all electronic Personal Health Information (ePHI) access, and new specifications for network segmentation, configuration management, anti-malware protection, patch management, software removal, incident response and breach notification.

Key topics included

  • Shared responsibility for HIPAA on AWS – A responsibility matrix mapping each §164.312 specification to what AWS manages nd what the customer must configure and operate.
  • ePHI boundary architecture – Guidance on establishing a defined ePHI boundary
  • ePHI data flow and encryption – A reference architecture tracing ePHI with the applicable §164.312 specification
  • Foundation checklist – Prerequisite recommendation before configuring individual Technical Safeguard controls.

This guidance is written for cloud architects, security engineers, CISOs, and compliance teams at covered entities and business associates building or operating AWS healthcare workloads. It assumes familiarity with AWS services and is intended as a practical implementation reference, not a legal or regulatory interpretation. This guidance focuses exclusively on Technical Safeguards.

HHS published a Notice of Proposed Rulemaking in January 2025, proposing significant updates to the HIPAA Security Rule—including eliminating the Addressable designation, making encryption, MFA, and asset inventory mandatory, and introducing new technical requirements not present in the current rule. As of June 2026, the final rule has not been published. This guidance covers both the current rule and the proposed changes and recommends treating all specifications as Required for new workloads.

Download HIPAA Security Rule on AWS: Technical Safeguards Implementation and Readiness Guidance.

For questions about HIPAA readiness on AWS, including Administrative Safeguards, Physical Safeguards, risk analysis, and assessment preparation, contact the AWS Security Assurance Services team or your AWS account representative.

This guidance is provided by AWS Security Assurance Services, LLC, a HITRUST External Assessor Firm and PCI-QSAC along with contribution from AWS HCLS, AWS Compliance teams. It is for informational and guidance purposes only and does not constitute legal, regulatory, or compliance advice. Recipients are solely responsible for determining applicability to their specific environments and legal obligations.

If you have feedback about this post, submit comments in the Comments section below.


Abdul Javid

Abdul Javid

Abdul is a Senior Security Assurance Consultant at AWS Security Assurance Services. He holds HITRUST certifications and has led HITRUST r2 and i1 engagements across multiple healthcare technology companies. Abdul holds multiple security and auditing certifications and supports customers building responsible AI governance programs on AWS. He has over 25 years of experience and holds certifications across AWS, CMMC, PCI DSS, PMI, ISC2, and ISACA.

Shreya Singh

Shreya Singh

Shreya is a Security Assurance Consultant at AWS with more than eight years of experience in governance, risk, compliance, and cloud security. She holds the CISA and HITRUST Certified CSF Practitioner (CCSFP) certifications and supports healthcare and technology organizations with HITRUST, HIPAA, SOC 2, risk management, and audit readiness initiatives.She holds a Master of Engineering in Cybersecurity from the University of Maryland, College Park.

Kapil Temghare

Kapil Temghare

Kapil is a Security Industry Specialist at AWS with over 10 years of experience spanning compliance, cloud security, and regulatory operations. He manages HIPAA compliance within the Regulatory Operations Center (ROC), including service eligibility assessments, controls validation, and compliance sign-off. Beyond healthcare, Kapil supports various regulatory programs such as FedRAMP and the EU Data Act and holds CISSP certification.

Hector Rodriguez

Hector Rodriguez

Hector is a Principal Industry Specialist and Executive Security Advisor, AWS Health & Life Sciences. He has over 25 years of experience enabling Health & Life Sciences business and clinical transformation and innovation and with multiple industry and academic groups. He is a board advisor for healthcare startups, a founding member of the HITRUST Business Associate Council and a health industry and cybersecurity curriculum advisor and lecturer.

Deliver Apache Kafka data to streaming tables for Apache Iceberg with Amazon MSK Express brokers

Post Syndicated from Shakhi Hali original https://aws.amazon.com/blogs/big-data/deliver-apache-kafka-data-to-streaming-tables-for-apache-iceberg-with-amazon-msk-express-brokers/

Today, we are announcing delivery to streaming tables on Apache Iceberg for Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express brokers, a fully managed capability that continuously materializes your streaming data as queryable Apache Iceberg tables on Amazon S3 Tables, a capability of Amazon Simple Storage Service (Amazon S3). With delivery to streaming tables, you no longer need to deploy, scale, or maintain Kafka connectors, Flink jobs, or custom consumers to make your streaming data available for analytics. You select a Kafka topic, choose S3 Tables as your destination, and your data becomes a read-only Iceberg table queryable from Amazon Athena, Amazon Redshift, and Apache Spark within minutes. Delivery to streaming tables provides up to 60% cost savings compared to self-managed alternatives. It also reduces downstream query costs by up to 30% through optimized file sizing, without writing a single line of code or managing any infrastructure. Because this capability delivers to S3 Tables registered in AWS Glue Data Catalog, your tables are automatically discoverable through Glue Data Catalog Business Context and Semantic Search (preview). Data stewards can enrich streaming tables with business descriptions, glossary terms, and skill assets. AI agents can then discover and reason in real time using semantic search grounded in trusted business definitions rather than raw schema inference.

In addition to S3 Tables, you can deliver Amazon MSK streaming data to general purpose Amazon S3 buckets in source data format. Data delivery to general purpose Amazon S3 buckets enables workloads like archival, backup, or ML training data delivery. This provides a price-performant, serverless, and scalable way to deliver streaming data as-is to your general purpose Amazon S3 buckets.

Challenges with delivering streaming data to Apache Iceberg

Customers today face three critical challenges when integrating streaming data with Apache Iceberg. First, ease of use: customers must manage complex Kafka Connect deployments, handle frequent pipeline failures, maintain custom configurations, handle data format conversions, and manage pipeline infrastructure for data delivery. These operational tasks consume significant engineering time and introduce ongoing risk of downtime. Second, resiliency: without proper coordination, simultaneous writes from multiple high-throughput Kafka partitions can conflict with each other, leading to failed commits, data freshness delays, and performance issues. Streaming ingestion of high-volume data creates large numbers of small Parquet files in Iceberg tables, significantly degrading query performance and forcing a difficult trade-off between data freshness and query efficiency. Third, price performance can become a bottleneck to enriching your data lake with streaming data into. With delivery to streaming tables, pricing is predictable, and up to 60% lower than self managed Kafka deployments, lowering the barrier to getting real-time context to your data agents.

How delivery to streaming tables solves these challenges

Delivery to streaming tables is a native capability built directly into Amazon MSK Express brokers. It addresses each challenge directly: it eliminates operational complexity by removing the need to deploy, configure, or maintain pipeline infrastructure, you enable it with a few clicks. It provides built-in write coordination and exactly-once delivery semantics, resolving concurrent writer conflicts and supporting data integrity without manual intervention. And it performs intelligent inline compaction during ingestion, producing query-optimized Parquet files that eliminate the small-file problem while maintaining minute-level data freshness. The capability automatically scales to process gigabytes per second of throughput.

End-to-end managed streaming analytics architecture

With delivery to streaming tables, you now have a fully managed end-to-end real-time data architecture from data ingestion through storage to analytics. Your producers publish events to Amazon MSK Express brokers, which continuously deliver data as optimized Iceberg read-only tables in S3 Tables, registered automatically on AWS Glue Data Catalog. From there, you can query your streaming data using analytics engines like Amazon Athena, Amazon Redshift, Amazon EMR (Apache Spark), or Apache Flink . You can also let AI agents discover and reason over your data through Glue Data Catalog semantic search. This managed experience eliminates the intermediate infrastructure that customers previously assembled, no separate connector clusters, no compaction jobs, no custom consumers, replacing it with a single, serverless pipeline from stream to insight.

The following diagram illustrates this end-to-end architecture.

End-to-end streaming architecture from Amazon MSK Express brokers to Iceberg tables in Amazon S3 Tables, queried by Athena, Redshift, EMR, and Flink

Getting started

To get started, log into the Amazon MSK console, navigate to your Amazon MSK Express cluster, and enable delivery to streaming tables with a few clicks. Specify the Kafka topic you want to deliver, configure your schema settings using AWS Glue Schema Registry, and choose your destination. Destinations can be either fully managed Iceberg tables in S3 Tables or self-managed Iceberg tables in general purpose S3 buckets. Once enabled, delivery to streaming tables immediately begins materializing your Kafka data as queryable Iceberg tables in S3 with no further intervention required.

Additionally, you can use Amazon MSK APIs to programmatically set up, update, or delete delivery to streaming tables configurations for your Kafka topics. This allows teams to build agentic workflows and infrastructure-as-code patterns for teams managing configurations across multiple clusters and topics at scale.

Getting started with the streaming tables Agent Skill

The streaming tables Agent Skill provides AI-assisted guidance for setting up streaming tables integrations for your existing or new topics in Amazon MSK Express cluster. The skill helps you configure delivery to S3 Tables (Iceberg) or S3, including schema registry setup, IAM role configuration, and validation.

Installing as an Agent Skill

Agent Skills are discovered automatically by compatible tools through the SKILL.md file. Refer to the Agent Toolit for AWS Skill Installation Guide to install the managing-amazon-msk Agent Skill. We also recommend you install the AWS MCP Server in your developer tool of choice, which exposes tools for searching AWS documentation, blogs, and Skills dynamically at runtime. These capabilities make agents more accurate and powerful for AWS related development and operational tasks, and make skill discovery and installation more flexible. Refer to Setting up the AWS MCP Server for guidance on installing the AWS MCP Server in your environment.

For example:

aws configure agent-toolkit
aws agent-toolkit add-skill --skill-name managing-amazon-msk

To verify the installation, interact with the skill in your preferred tool.

To start delivering data from your Kafka topics to Apache Iceberg tables in real time, for example, prompt “Create me a streaming table on my MSK cluster for my events topic” to your agent of choice:

Agent chat showing the prompt to create a streaming table on an MSK cluster for the events topic

The agent will dynamically load the managing-amazon-msk skill, and start by gathering the available resources in your AWS account to use for the streaming tables integration. Once it gathers that data, it will confirm the resources to use or create, and create the integration:

Agent confirming the AWS resources to use and creating the streaming tables integration

After creating the integration, the agent will summarize the status and can then help with any other operational tasks with your data. For example, the agent can help you set up AWS Lake Formation permissions for you to query the data in S3 Tables with Athena, or configure your table maintenance behavior in S3 Tables:

Agent summarizing integration status and offering to set up Lake Formation permissions or configure S3 Tables maintenance

Conclusion

Delivery to streaming tables and general purpose S3 buckets is available in all AWS Regions where Amazon MSK Express brokers are available. To learn more about delivery to streaming tables, visit the documentation and pricing pages.


About the authors

Shakhi Hali

Shakhi Hali

Shakhi is a Product Manager for Amazon Managed Streaming for Apache Kafka. She works closely with AWS customers to understand their needs for real-time analytics and high throughput, low latency streaming workloads. Working backwards from their needs, she helps drive the Amazon MSK roadmap and deliver new innovations that help AWS customers focus on building novel streaming applications.

Mazrim Mehrtens

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. Mazrim works with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

Huyam Hasan

Huyam Hasan

Huyam is a Solutions Architect II at AWS, based in Austin, TX, with a passion for data and analytics solutions and customer success. She works with enterprise customers across travel, gaming, and hospitality to design and build modern, secure, and scalable data and streaming architectures, with a focus on real-time analytics that help them achieve their business outcomes.

Extend Amazon Inspector SBOM Generator with Plugins

Post Syndicated from Michael Long original https://aws.amazon.com/blogs/security/extend-amazon-inspector-sbom-generator-with-plugins/

Amazon Inspector is an automated vulnerability management service that continually scans Amazon Web Services (AWS) workloads for software vulnerabilities. The vulnerability management capabilities of Amazon Inspector are powered by an asset inventory engine known as the Amazon Inspector SBOM Generator (inspector-sbomgen), a standalone command-line tool that produces a software bill of materials (SBOM) from container images, directories, archives, local systems, compiled binaries, and more. Over the past two years, we’ve expanded inspector-sbomgen’s coverage across dozens of programming language ecosystems, operating systems, and widely deployed applications.

We’re pleased to announce a new capability for builders using inspector-sbomgen: a plugin system for writing your own custom package collectors that you can use right away, without requiring source code compilation nor waiting for an official release.

You can download the latest version of inspector-sbomgen from the Amazon Inspector User Guide.

In this post, we walk you through what the inspector-sbomgen plugin system does, why we built it, and how you can write your first plugin in a few minutes. Along the way, we also cover how plugin-generated package components integrate with Amazon Inspector for vulnerability scanning, and we explore the plugin safety model, which helps ensure security-hardened and predictable plugin behavior.

Why we built a plugin system

Software ecosystems are dynamic. New language package managers, lockfile formats, and end user applications ship constantly, and many are adopted quickly, in some cases with little security scrutiny. That leaves security teams with a visibility gap: production workloads running software that their SBOM tooling doesn’t yet recognize. Customers have asked us to inventory many of these ecosystems directly, and until recently, the only path to support was to open a feature request and wait for the inspector-sbomgen team to onboard the ecosystem and deploy a new release.

The inspector-sbomgen plugin system changes that. With plugins, you can:

  • Onboard ecosystems that inspector-sbomgen doesn’t support out of the box. New open source ecosystems, niche or fast-moving package formats, and internal or proprietary tooling can all be inventoried without modifying inspector-sbomgen.
  • Prototype detection for an ecosystem quickly. We designed a plugin system that is friendly to developers and AI coding assistants alike. Plugins are written in Lua, loaded at runtime, and require no Go toolchain nor compilation. You can use the built in test harness to iterate on a plugin and see results immediately.
  • Build on a stable foundation. The plugin API abstracts away artifact-type differences, so you write your detection logic once and it works seamlessly across container images, archives, local systems, and more. And because plugins stay decoupled from the internals of sbomgen, the core tool’s regression surface stays small.

Internally, we’ve used the plugin system to ship new ecosystem coverage faster than before. In our 1.13 release, more than 20 ecosystems that were previously implemented in Go, including Apache Tomcat, NGINX, MySQL, Redis, WordPress, and the OpenSSH toolchain, are now embedded as plugins inside the sbomgen binary. The same release also added more than ten brand-new ecosystems as plugins, including Apache Cassandra, Apache Struts, Conda, Swift packages, and AI-agent collectors (Amazon Q Developer, Kiro CLI, Claude Code, GitHub Copilot, and Ollama).

How inspector-sbomgen plugins work

Sbomgen plugins follow a two-step pipeline:

  1. Discovery – Scan the artifact’s file system to identify files that contain installed package metadata.
  2. Collection – Open each discovered file, parse file contents, and publish findings into the SBOM.

Under the hood, an event bus connects discovery and collection plugins. Discovery plugins publish events listing discovered files, and one or more collection plugins subscribe to these events, triggering package collection. Developers might recognize this behavior as the observer pattern.

This decoupling lets a single discovery plugin feed multiple collectors, for example, one extracting package metadata, another scanning for secrets, and another checking policy. Each collection plugin works from the same file list without re-walking the artifact filesystem, a computationally expensive operation.

Write your first plugin in 5 minutes

Inspector-sbomgen makes it straightforward to bootstrap a plugin environment. The plugin new command tells sbomgen to create a new plugin workspace, and the —-with-example flag populates the workspace with a discovery-collection plugin pair, that you can run immediately.

inspector-sbomgen plugin new --with-example 

After invoking the preceding command, you will be prompted to provide a plugin name and a directory that will contain your plugin workspace. You can provide custom values or use the default values:

Plugin name (identifies the software ecosystem your plugin will inventory, e.g. debian-dpkg, rhel-rpm, python-pip, cmake) [my-custom-ecosystem]: <enter>
Project directory [my-sbomgen-plugins]: <enter>

Created plugin "my-custom-ecosystem" in my-sbomgen-plugins/

Note that you can skip interactive prompts by specifying the plugin name and directory using the corresponding command line interface (CLI) arguments:

inspector-sbomgen plugin new \
    --with-example \
    --name my-custom-ecosystem \
    --path my-sbomgen-plugins

After creating your plugin workspace, inspector-sbomgen will display a next steps screen, which guides developers and AI code assistants to the source files they need to change and to supporting documentation:

Next steps:

  Get started:
    1. Open plugin folder in a code editor (VS Code recommended)
    2. Add test files that your plugin will discover and parse
       (e.g., config files, lockfiles, binaries, etc.):
       my-sbomgen-plugins/discovery/cross-platform/extra-ecosystems/my-custom-ecosystem/_testdata/

  Develop:
    3. Edit discovery:    my-sbomgen-plugins/discovery/cross-platform/extra-ecosystems/my-custom-ecosystem/init.lua
    4. Edit collection:   my-sbomgen-plugins/collection/cross-platform/extra-ecosystems/my-custom-ecosystem/init.lua

  Test:
    5. Write unit tests:  my-sbomgen-plugins/discovery/cross-platform/extra-ecosystems/my-custom-ecosystem/init_test.lua
    6. Run unit tests:    inspector-sbomgen plugin test --path my-sbomgen-plugins

  Deploy:
    7. Distribute your plugin directory wherever you run inspector-sbomgen:
       inspector-sbomgen <arguments> --plugin-dir /path/to/my-sbomgen-plugins

       Example:
       inspector-sbomgen container --image alpine:latest -o /tmp/sbom.json --plugin-dir /path/to/my-sbomgen-plugins

For code completion, install the VS Code Lua language server extension:
  https://luals.github.io/#vscode-install

For more information:
  - Plugin guide:    my-sbomgen-plugins/docs/sbomgen-plugin-developer-guide.md
  - Testing guide:   my-sbomgen-plugins/docs/sbomgen-plugin-testing-guide.md
  - API reference:   my-sbomgen-plugins/docs/sbomgen-plugin-api-reference.md
  - Documentation:   https://docs.aws.amazon.com/inspector/latest/user/sbom-generator.html

Now that you have a plugin workspace, let’s explore its contents in greater detail:

tree my-sbomgen-plugins

├── AGENTS.md
├── collection
│   └── cross-platform
│       └── extra-ecosystems
│           └── my-custom-ecosystem
│               └── init.lua
├── discovery
│   └── cross-platform
│       └── extra-ecosystems
│           └── my-custom-ecosystem
│               ├── _testdata
│               │   ├── empty
│               │   └── example.lock
│               ├── init_test.lua
│               └── init.lua
├── docs
│   ├── sbomgen-plugin-api-reference.md
│   ├── sbomgen-plugin-developer-guide.md
│   └── sbomgen-plugin-testing-guide.md
├── library
│   └── sbomgen.lua
└── README.md

The scaffolded project includes a working discovery and collection plugin pair, passing unit tests with test fixtures under _testdata/, a .vscode/settings.json for integrated development environment (IDE) integration, and a local copy of the developer documentation.

The scaffolding is deliberately succinct and complete, so it reads well for both humans and AI coding assistants. Every file has clear comments that explain what each function does and what the plugin author needs to fill in.

To test a plugin, you first need something to scan, such as a package lock file or a compiled binary. The example plugin inventories a fictional example.lock with the following contents:

my-package-alpha==1.0.0 
my-package-beta==2.3.1 
my-package-gamma==0.9.5 

The provided discovery plugin knows how to look for instances of example.lock within the artifact file system:

-- my-custom-ecosystem discovery plugin
-- Discovers example.lock files in the artifact file list.

function discover()
    return sbomgen.find_files_by_name({"example.lock"})
end

And the provided collection plugin knows how to parse the contents of example.lock and publish package findings to the output SBOM.

-- my-custom-ecosystem collection plugin
-- Parses example.lock files and extracts package name and version.

function collect(file_path)
    local content = sbomgen.read_file(file_path)
    if content == nil then
        return
    end

    for line in content:gmatch("[^\n]+") do
        local name, ver = line:match("^(.+)==(.+)$")
        if name and ver then
            sbomgen.push_package({
                name = name,
                version = ver,
                purl_type = "generic",
                namespace = "my-custom-ecosystem",
                component_type = sbomgen.component_types.APPLICATION,
            })
        end
    end
end

Run the tests

Plugins ship with a built-in test framework so you can validate your logic before scanning a real artifact. Tests are written in Lua, live next to the plugin in init_test.lua, and reference fixture data in _testdata/:

function test_discovers_packages() 
    local result = testing.scan_directory("_testdata") 
    testing.assert_equals(3, #result.findings) 
    testing.assert_equals("my-package-alpha", result.findings[1].name) 
    testing.assert_equals("1.0.0", result.findings[1].version) 
end 
 
function test_no_findings_for_empty_directory() 
    local result = testing.scan_directory("_testdata/empty") 
    testing.assert_equals(0, #result.findings) 
end

Run the tests with the following command:

inspector-sbomgen plugin test --path my-sbomgen-plugins -v

=== RUN   my-custom-ecosystem/discovery/init_test/test_discovers_packages 
--- PASS: my-custom-ecosystem/discovery/init_test/test_discovers_packages (0.04s) 
=== RUN   my-custom-ecosystem/discovery/init_test/test_no_findings_for_empty_directory 
--- PASS: my-custom-ecosystem/discovery/init_test/test_no_findings_for_empty_directory (0.04s) 
ok    2 tests passed 

This is the tightest development loop we could design: no Go toolchain, no rebuild, no container spin-up. Write a test, run it, iterate.

Scan a real artifact

For plugins to produce findings, inspector-sbomgen needs an artifact that contains the files your plugin looks for. For the example plugin, any directory with an example.lock file works. The fixture we generated earlier is a good stand-in:

inspector-sbomgen directory \ 
    --plugin-dir ./my-sbomgen-plugins \ 
    --path ./my-sbomgen-plugins/discovery/cross-platform/extra-ecosystems/my-custom-ecosystem/_testdata \ 
    -o sbom.json 

The --plugin-dir flag tells inspector-sbomgen where to load your Lua plugins from. The resulting SBOM contains a CycloneDX component for each of the three packages in example.lock, for example:

{
  "bom-ref": "comp-2",
  "type": "application",
  "name": "my-package-alpha",
  "version": "1.0.0",
  "scope": "optional",
  "purl": "pkg:generic/my-sbomgen-plugin/[email protected]",
  "properties": [
    {
      "name": "amazon:inspector:sbom_generator:source_path",
      "value": "./my-sbomgen-plugins/example.lock"
    }
  ]
}

Every plugin-generated component carries an amazon:inspector:sbom_generator:source_path property that records the file the component was collected from, so you can always trace a component back to the artifact that produced it.

Vulnerability scanning with Amazon Inspector

Plugin-generated findings are first-class SBOM components. They work with every downstream consumer that reads CycloneDX SBOMs, including Amazon Inspector. To send an SBOM to Amazon Inspector for vulnerability analysis, add the --scan-sbom flag (this requires an active AWS account):

inspector-sbomgen directory \ 
    --path ./my-sbomgen-plugins/discovery/cross-platform/extra-ecosystems/my-custom-ecosystem/_testdata \ 
    --plugin-dir ./my-sbomgen-plugins \ 
    --scan-sbom \ 
    --aws-profile your_profile \ 
    --aws-region your_region \ 
    -o /tmp/sbom.json 

An important caveat when you onboard a brand-new ecosystem: Plugin authors can inventory arbitrary ecosystems, but Amazon Inspector can only report vulnerabilities for components it has advisories for. When you point Amazon Inspector at a component whose ecosystem isn’t in its advisory feeds yet, Inspector will return the component with a property, Component skipped: no supported rules found. For example:

{ 
  "bom-ref": "comp-1", 
  "name": "my-package-alpha", 
  "properties": [ 
    { 
      "name": "amazon:inspector:sbom_scanner:path", 
      "value": "my-sbomgen-plugins/discovery/cross-platform/extra-ecosystems/my-custom-ecosystem/_testdata/example.lock" 
    }, 
    { 
      "name": "amazon:inspector:sbom_scanner:info", 
      "value": "Component skipped: no supported rules found." 
    } 
  ], 
  "purl": "pkg:generic/my-custom-ecosystem/[email protected]", 
  "type": "application", 
  "version": "1.0.0" 
} 

This is expected behavior, not an error. The SBOM is still generated correctly, the component is still tracked, and the source_path tells you exactly which file produced it. If and when Amazon Inspector adds advisory coverage for the ecosystem, the same SBOM will start producing vulnerability findings without any change to your plugin. For ecosystems Inspector already supports, plugin-generated components are indistinguishable from components produced by built-in scanners.

First class IDE support

We care about productivity and efficiency when writing plugins. Writing Lua without modern conveniences such as autocomplete isn’t fun, so every plugin project scaffolded with the plugin new command ships with a library/sbomgen.lua definition file and a .vscode/settings.json that automatically wires it up to the Lua Language Server extension for VS Code.

For code completion and IDE support, first install the sumneko.lua extension, open your plugin project in VS Code, and every sbomgen.* function will get:

  • Parameter hints with types.
  • Hover documentation.
  • Autocomplete for constants (sbomgen.component_types.*, sbomgen.groups.*, sbomgen.platform.*).
  • Type checking on function calls.
  • Inline warnings when required fields are missing from push_package().

The same definition file makes plugin development work well with AI coding assistants. The types and documentation are embedded in a form that tools can read, so assistants can generate correct plugin code with far less monitoring than writing against a raw language would require.

A safe foundation

Plugins run real code inside the same process as inspector-sbomgen, so we designed the execution environment to keep that code stable and security-hardened. Every Lua plugin runs in an isolated sandbox. Every Lua virtual machine (VM) has access to a restricted subset of the Lua standard library to ensure only safe operations are permitted:

  • No direct filesystem access. The Lua io library isn’t loaded. All file operations go through sbomgen.* functions, which route through sbomgen’s internals so your plugin behaves identically whether it’s scanning a directory on disk, a container image, a compressed archive, or a mounted volume.
  • No subprocess execution or environment mutation. The Lua os library is blocked, so plugins can’t spawn processes, modify environment variables, or touch files outside the artifact.
  • No VM introspection. The Lua debug library is blocked.
  • No unbounded code loading. dofile, loadfile, and loadstring are removed. require() is available but restricted to the plugin’s own directory tree, so plugins can share helper modules with themselves but cannot load code from other plugins or system paths.

If a plugin raises an unhandled Lua error, inspector-sbomgen logs a warning and continues with the next file or plugin; one faulty plugin does not prevent other plugins from running. Plugins never override inspector-sbomgen’s built-in package collectors. Every plugin must declare a unique name. If a custom plugin uses a name that’s already claimed by an official built-in plugin, the custom plugin is skipped with a warning. Built-in plugins always take precedence, so a custom plugin can never silently replace or shadow the tool’s own detection behavior.

Next steps

To start building your own plugins today:

  1. Install the latest inspector-sbomgen from the Amazon Inspector user guide.
  2. Run inspector-sbomgen plugin new --with-example and follow the prompts.
  3. Run inspector-sbomgen plugin test --path ./my-sbomgen-plugins -v to see the example tests pass.
  4. Replace the example logic with detection for your own ecosystem.

The full reference documentation covers every function, constant, and command in depth:

Conclusion

Whether you’re adding support for an internal lockfile format, prototyping detection for a new open source ecosystem, or replacing a home-grown scanner with something your whole organization can run at scale, the plugin system is designed to make the path from idea to working SBOM as short as possible. We can’t wait to see what you build with it.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.


Michael Long

Michael Long

Michael is a Senior Security Researcher for Amazon Inspector at AWS. He leads research and development of the Amazon Inspector SBOM Generator and Amazon Inspector for GitHub Actions. Before joining AWS, he was a principal adversary emulation engineer on the MITRE ATT&CK team. He also served honorably for nearly 10 years in the U.S. Army spanning military intelligence and cyber operations.

Charlie Bacon

Charlie Bacon

Charlie is Head of Security Engineering and Research for Amazon Inspector at AWS. He leads the teams behind the vulnerability scanning and inventory collection services that power Amazon Inspector and other Amazon Security vulnerability management tools. Before joining AWS, he spent two decades in the financial and security industries where he held senior roles in both research and product development.

Anthony Verleysen

Anthony Verleysen

Anthony is a Senior Technical Product Management for Amazon Inspector. Before Amazon Inspector, Anthony worked as a Product Manager in AWS Systems Manager owning Node Management capabilities. Outside of work, Anthony is an avid tennis and soccer player.